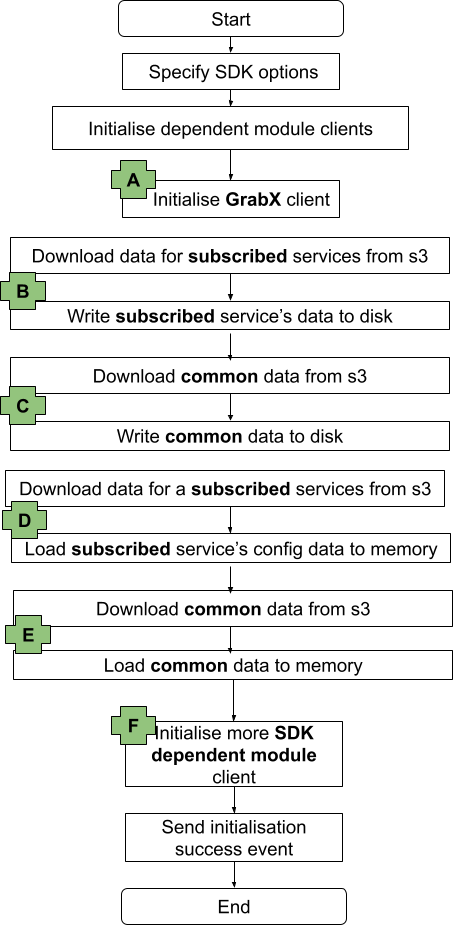Tag Archives: Engineering

Embracing passwordless authentication with Grab’s Passkey

Post Syndicated from Grab Tech original https://engineering.grab.com/embracing-passwordless-authentication-with-passkey

Abstract

This blog post introduces Passkey — our latest addition to the Grab app — a step towards a secure, passwordless future. It provides an in-depth look at this innovative authentication method that allows users to have full control over their security, making authentication seamless and phishing-resistant. By the end of this piece, you will understand why we developed Passkey, how it works, the challenges we overcame, and the benefits brought to us post-launch. Whether you’re a tech enthusiast, a cybersecurity follower, or a Grab user, this piece offers valuable insights into the passwordless authentication sphere and Grab’s commitment to user safety and comfort.

Introduction

In the evolving world of digital security, Grab has always prioritised user account safety. A significant part of this involves exploring more secure and user-friendly authentication methods. Enter Grab’s Passkey — a major step towards passwordless authentication that leverages the Fast IDentity Online (FIDO) standard, giving users full control over their security, and making authentication seamless.

Background

Traditionally, the authentication process primarily relies on passwords — a precarious practice given the vulnerability to various security threats, such as phishing, keystroke logging, and brute-force attacks. This downside leads to the pursuit of safer, more user-friendly alternatives. Among these is the introduction of passwordless authentication.

A passwordless authentication method eliminates the need for users to enter traditional passwords during the verification process. Instead, it employs alternatives like:

  • Email link: A one-time clickable link sent via email.
  • One-Time Passcodes (OTPs): Temporary codes sent to users.
  • Social logins: Using existing profiles on platforms like Facebook or Google to sign in.
  • Authenticator apps: Software that generates time-sensitive codes.

Solution

Recognising the limitations and security issues of traditional password-based authentication, we turned to a more secure, user-friendly solution – the passwordless authentication system. Among other methods, we are also enabling Passkey, built on the FIDO standard. This global standard fosters wider adoption and support from consumer brands, making Passkey a secure and convenient choice.

Why Passkey?

Given the rapidly evolving security threats in the digital space, we selected Passkey for its unique benefits in providing both enhanced security and a seamless user experience. Passkey offers enhanced security as it is phishing-resistant and doesn’t require secrets to be stored in Grab’s database. Instead, secrets are securely kept within the user’s device, putting the control in their hands and significantly reducing the chances of exposure.

Fast-paced adoption of Passkey

Passkey technology is not only promising in theory but also successful in practice, as evidenced by its wider industry adoption. Consumers are adopting passkeys at a rapid pace in 2024. With large global consumer brands, such as Adobe, Amazon, Apple, Google, Hyatt, Nintendo, PayPal, Playstation, Shopify and TikTok enabling passkey technology for their users, more than 13 billion accounts can now leverage passkeys for sign-in.

In a recent FIDO Alliance independent study conducted on World Password Day 2024 across the U.S. and UK, findings reveal:

  • A majority of people are aware of passkey technology (62%).
  • Over half have enabled passkeys on at least one of their accounts (53%).
  • Once they adopt a passkey, nearly a quarter enable a passkey whenever possible (23%).
  • A large number believe passkeys are more secure (61%) and more convenient than passwords (58%).

These trends clearly illustrate why we chose to implement Passkey as our passwordless solution.

Architecture details

How do passkeys work?

There are three components of the passkey flow:

  • Backend: Holds the accounts database storing the public key and other metadata about the passkey.
  • Frontend: Communicates with the authenticator and sends requests to the backend.
  • Authenticator: The user’s authenticator creates and stores the passkey. This may be implemented in the operating system underlying the user agent, in external hardware, or a combination of both.
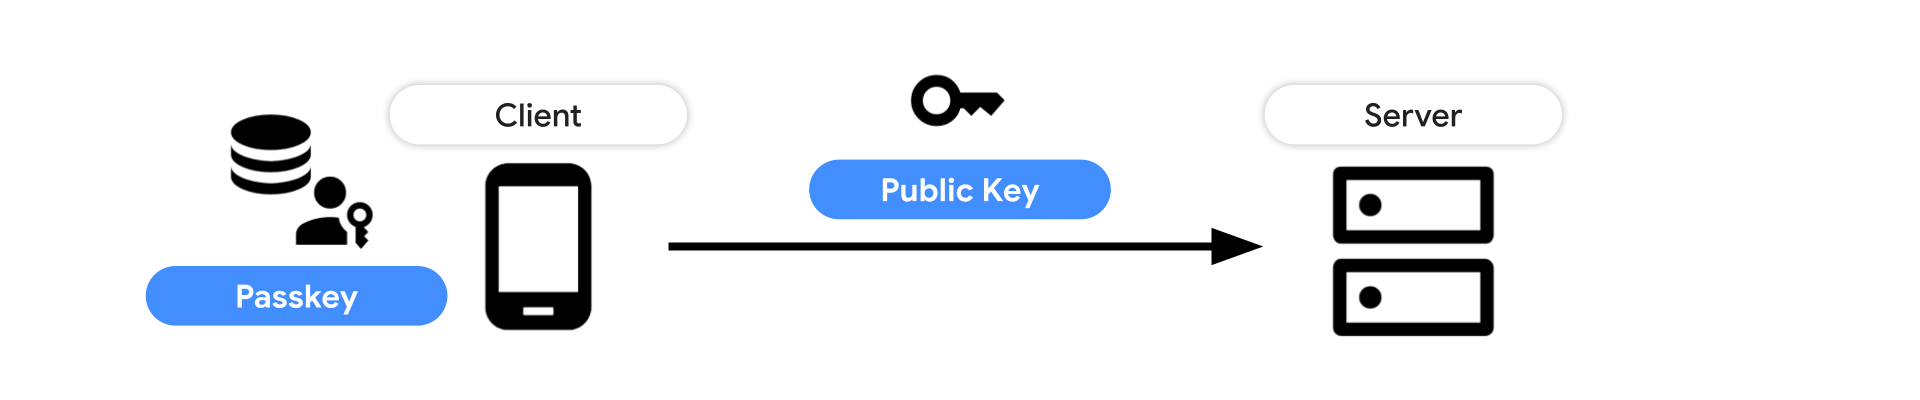
Figure 1. A high-level overview of the passkey authentication.

Supported environments

Google Password Manager: Stores, serves and synchronises passkeys on Android and Chrome. Passkeys are securely backed up and synced between Android devices where the user is signed using the same Google account, and available passkeys are listed.

iCloud Keychain: Synchronises the saved passkey to other Apple devices that run macOS, iOS, or iPadOS where the user is signed in using the same iCloud account.

Implementation

In this section, we illustrate the usage of passkeys in several scenarios.

Creating a new passkey
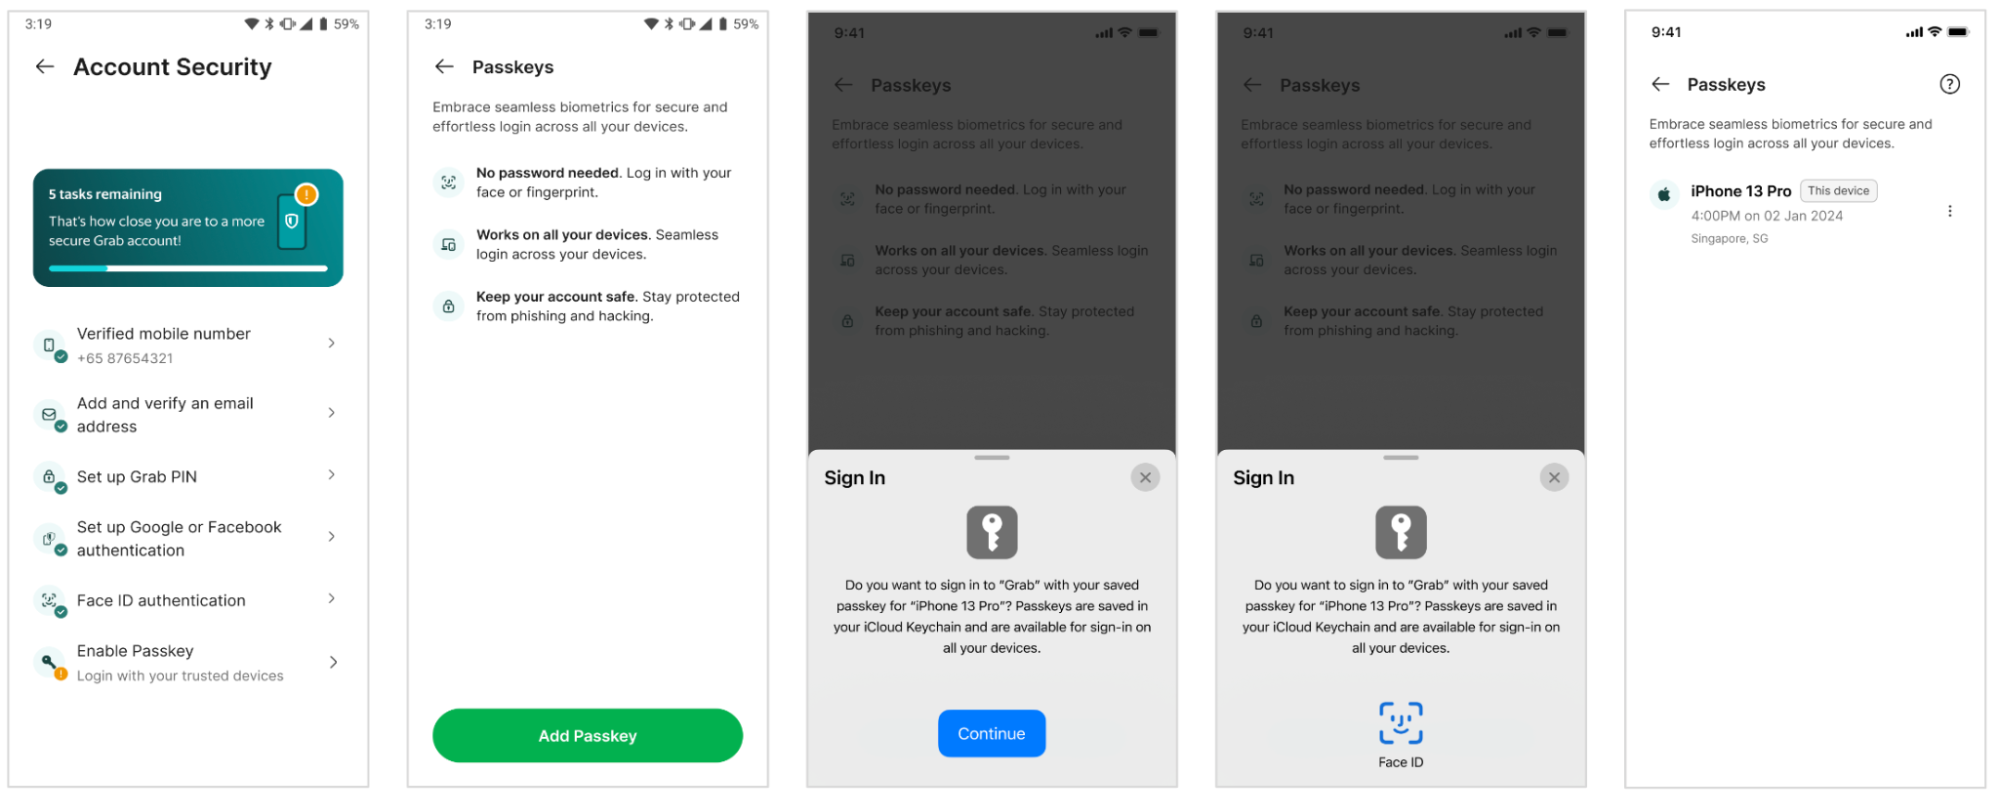
Figure 2. Passkey registration steps in Grab app.
  1. The user signs into the Grab app and selects Enable Passkey.
  2. Frontend requests user details and a challenge from Backend.
  3. Authenticator creates the user’s passkey upon their consent using their device’s screen lock.
  4. This passkey, along with other data, is sent back to Frontend.
  5. Frontend sends the public key credential to Backend for storage and future authentications.
Figure 3. Sequence diagram of Passkey registration.

Creating a passkey – notable Webauthn parameters

  1. When the user selects Enable Passkey, Frontend fetches the following information to call navigator.credentials.create() from Backend:
    • challenge: server-generated challenge.
    • user.id: user’s unique ID, stored as ArrayBuffer.
    • user.name: unique username or email for account recognition.
    • user.displayName: user-friendly name for the account.
    • excludeCredentials: to prevent registering the same device multiple times.
    • rp.id: Domain or a registrable suffix of an RP’s origin.
    • rp.name: Name of the RP.
    • pubKeyCredParams: Specifies RP’s public-key algorithms.
    • authenticatorSelection.authenticatorAttachment: Indicates type of authenticator attachment desired.
    • authenticatorSelection.requireResidentKey: Indicates if resident key is needed.
    • authenticatorSelection.userVerification: Indicates if user verification is required, preferred, or discouraged.
  2. Frontend invokes WebAuthn API to create a passkey.

     const publicKeyCredentialCreationOptions = {
       challenge: *****,
       rp: {
         name: "Example",
         id: "example.com",
       },
       user: {
         id: *****,
         name: "john78",
         displayName: "John",
       },
       pubKeyCredParams: [{alg: -7, type: "public-key"},{alg: -257, type: "public-key"}],
       excludeCredentials: [{
         id: *****,
         type: 'public-key',
         transports: ['internal'],
       }],
       authenticatorSelection: {
         authenticatorAttachment: "platform",
         requireResidentKey: true,
       }
     };
    
     const credential = await navigator.credentials.create({
       publicKey: publicKeyCredentialCreationOptions
     });
    
     // Encode and send the credential to the server for verification.
    
  3. Post user consent, passkey is created and returned along with relevant data to the frontend.
  4. Frontend sends the public key credential to Backend where it gets stored for future authentication.
  5. Backend receives and processes the object, and information is stored in the database for future use.

Signing in with a passkey
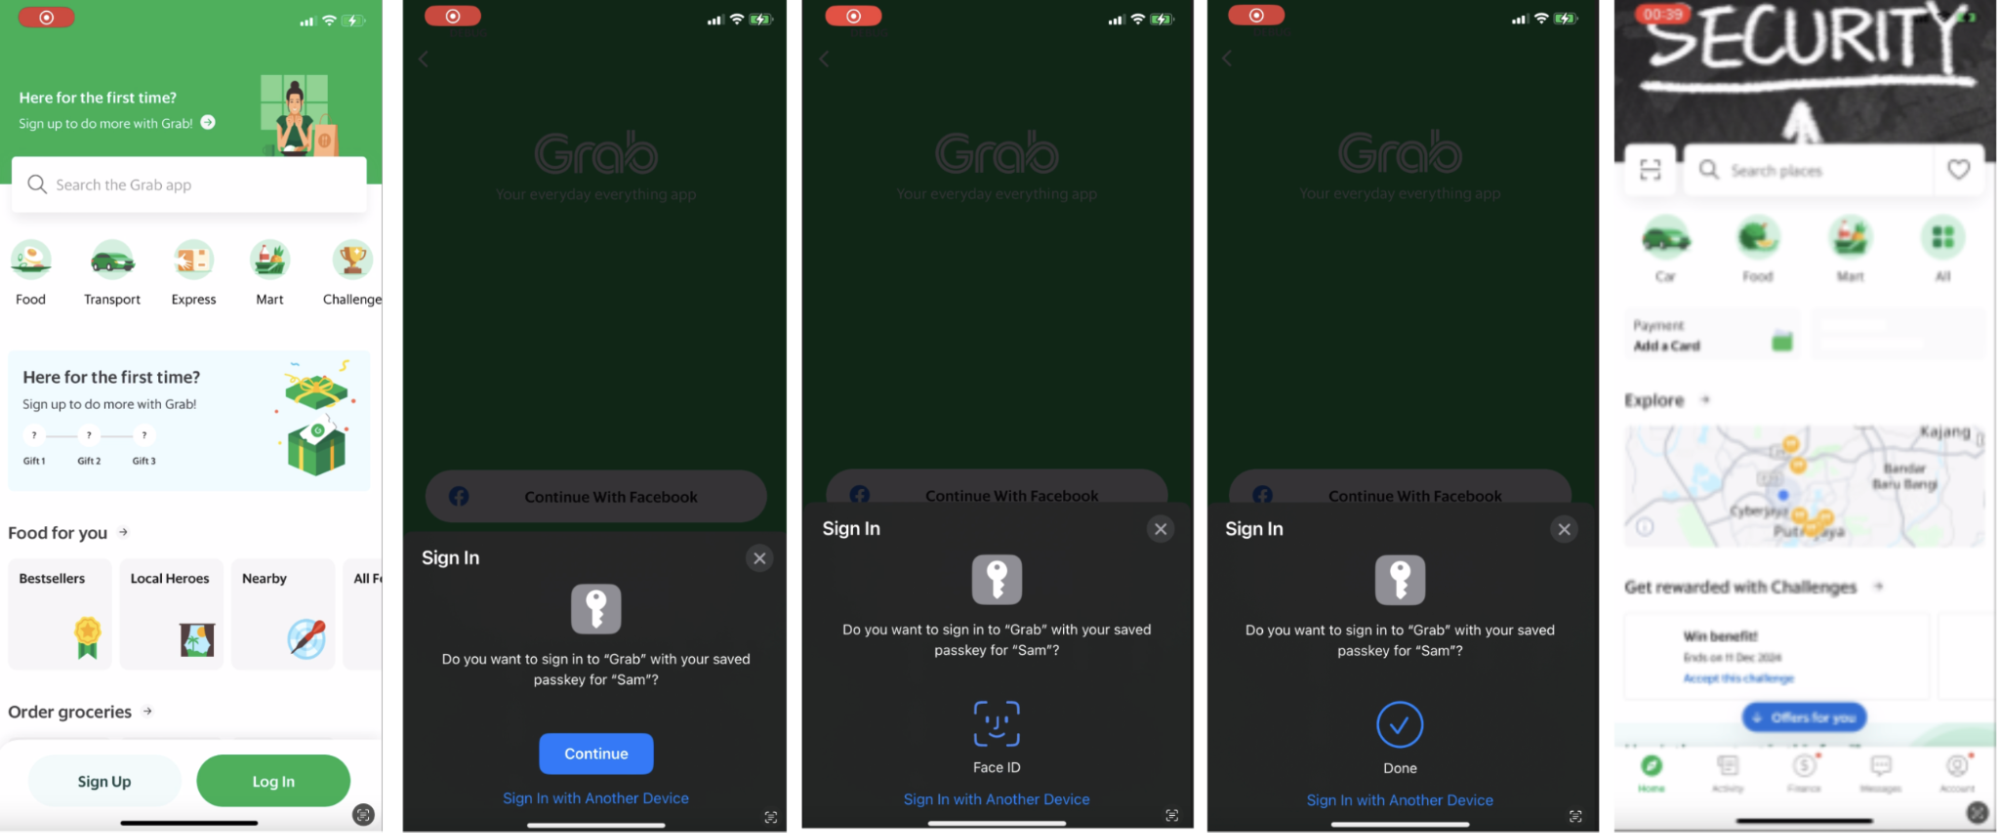
Figure 4. Passkey authentication steps in Grab app.
  1. The user launches the Grab app and opts to login using their passkey.
  2. Frontend requests a challenge from Backend for passkey authentication.
  3. The user is shown their available passkeys.
  4. Upon choosing a passkey, the user consents to using their device’s lock screen.
  5. Frontend receives the public key credential and some data.
  6. Frontend forwards these to the backend, which verifies them against the database and logs the user in.

Thus, Passkey enhances the login experience, providing an optimal blend of security and seamless usability.
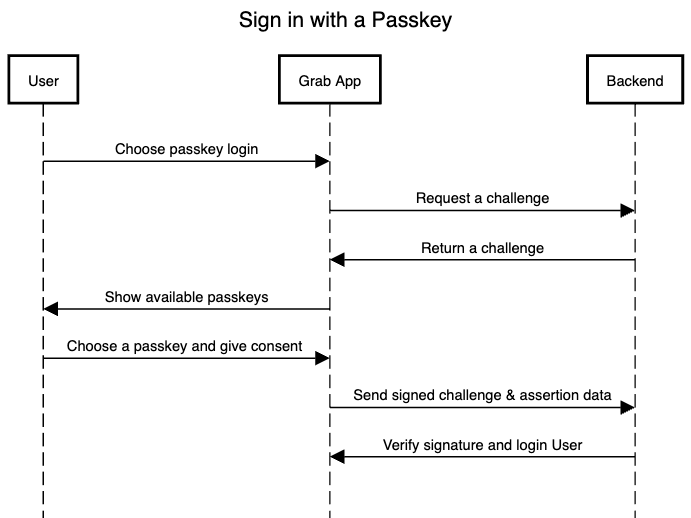
Figure 5. Sequence diagram of the Passkey authentication.

Signing in with a passkey – notable Webauthn parameters

  1. Frontend fetches a challenge from Backend.
    • challenge: server-generated challenge, crucial to prevent replay attacks.
    • allowCredentials: array of acceptable credentials for authentication.
    • userVerification: indicates whether user verification is required, preferred, or discouraged.
  2. Frontend calls navigator.credentials.get() to initiate user authentication.

     // To abort a WebAuthn call, instantiate an `AbortController`.
    
     const abortController = new AbortController();
    
     const publicKeyCredentialRequestOptions = {
       // Server generated challenge
       challenge: ****,
       // The same RP ID as used during registration
       rpId: 'example.com',
     };
    
     const credential = await navigator.credentials.get({
       publicKey: publicKeyCredentialRequestOptions,
       signal: abortController.signal,
       // Specify 'conditional' to activate conditional UI
       mediation: 'conditional'
     });
    
  3. Post user consent through their device’s screen lock, a PublicKeyCredential object is returned to Frontend.
  4. The returned PublicKeyCredential is sent to Backend for verification. Backend looks up matching credential ID and verifies the signature against the stored public key.

Impact

A frictionless login paints a positive picture for our users. No more waiting for OTPs or struggling with cumbersome two-factor authentication. With the implementation of Passkey, users will enjoy a smoother, faster, and more secure login process.

In addition to delivering a frictionless user experience, passkeys provide heightened security compared to conventional authentication methods such as OTPs and passwords, which demand active credential management.

Using passkeys for authentication can lead to cost savings by cutting down or eliminating fees related to third-party authentication services, communication expenses, and messaging platforms. This strategy not only boosts security and user experience but also enhances the financial efficiency of the authentication process.

Moving forward, our focus is on enhancing, streamlining, and extending the capabilities of Passkey. We are enthusiastic about the evolution of passwordless authentication and are dedicated to ongoing investments in technologies that deliver the utmost user satisfaction and experience.

Conclusion

Leveraging passkeys for authentication provides heightened security, enhanced user experience, cost-effectiveness, decreased vulnerabilities, multi-factor authentication support, and simplified credential management. The future direction involves enhancing and broadening Passkey capabilities, with a dedication to investing in user-centric technologies that advance passwordless authentication. This commitment underscores the focus on delivering secure, efficient, and user-friendly authentication solutions for both existing and prospective users.

What’s next

Looking ahead, based on the user adoption of Passkey and its anticipated impact on improving login convenience, we aim to explore the expansion of this feature to web login as well. We envision a scenario where users can leverage the power of their existing phone Passkey, no matter the operating system, thereby creating a truly seamless and secure login experience.
As we gather user feedback, analyse usage data, and delve into Passkey’s impact, we aim to identify growth opportunities and further enhance our understanding of this innovative feature’s transformative effect on app security. Stay tuned for updates on how we are revolutionising our approach to authentication, with a continuous focus on enhancing user convenience and security.

References

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Cloud Efficiency at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/cloud-efficiency-at-netflix-f2a142955f83

By J Han, Pallavi Phadnis

Context

At Netflix, we use Amazon Web Services (AWS) for our cloud infrastructure needs, such as compute, storage, and networking to build and run the streaming platform that we love. Our ecosystem enables engineering teams to run applications and services at scale, utilizing a mix of open-source and proprietary solutions. In turn, our self-serve platforms allow teams to create and deploy, sometimes custom, workloads more efficiently. This diverse technological landscape generates extensive and rich data from various infrastructure entities, from which, data engineers and analysts collaborate to provide actionable insights to the engineering organization in a continuous feedback loop that ultimately enhances the business.

One crucial way in which we do this is through the democratization of highly curated data sources that sunshine usage and cost patterns across Netflix’s services and teams. The Data & Insights organization partners closely with our engineering teams to share key efficiency metrics, empowering internal stakeholders to make informed business decisions.

Data is Key

This is where our team, Platform DSE (Data Science Engineering), comes in to enable our engineering partners to understand what resources they’re using, how effectively and efficiently they use those resources, and the cost associated with their resource usage. We want our downstream consumers to make cost conscious decisions using our datasets.

To address these numerous analytic needs in a scalable way, we’ve developed a two-component solution:

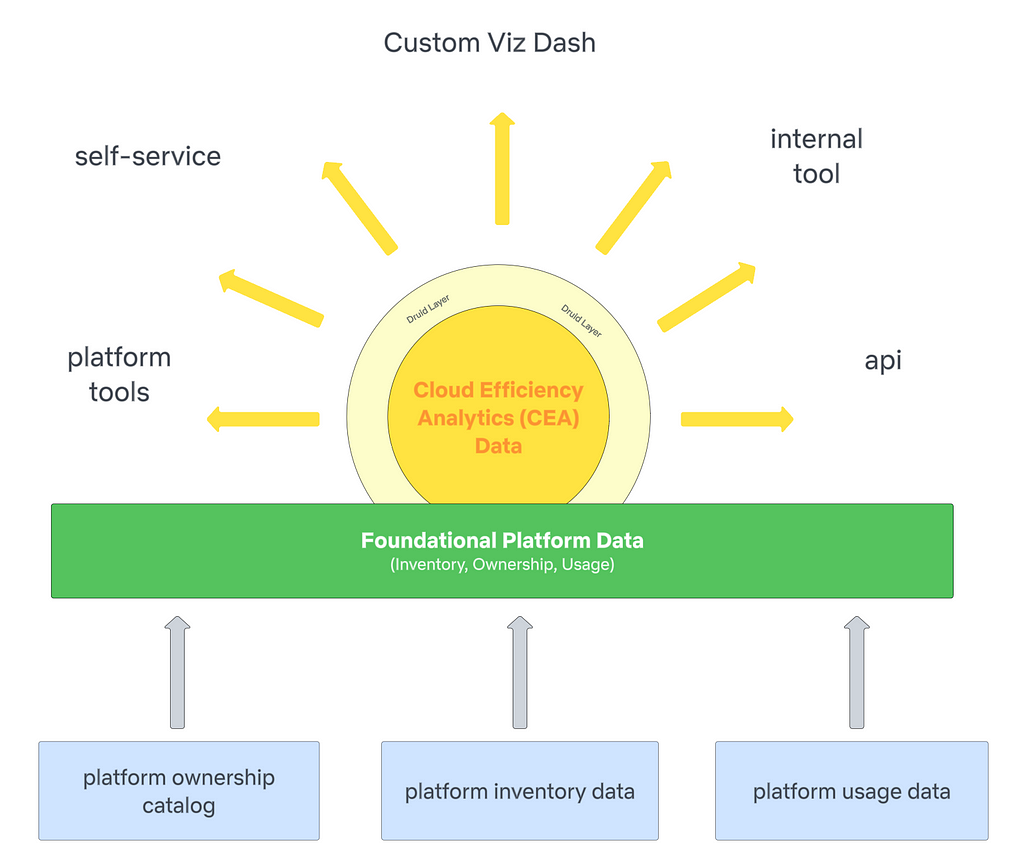
  1. Foundational Platform Data (FPD): This component provides a centralized data layer for all platform data, featuring a consistent data model and standardized data processing methodology.
  2. Cloud Efficiency Analytics (CEA): Built on top of FPD, this component offers an analytics data layer that provides time series efficiency metrics across various business use cases.

Foundational Platform Data (FPD)

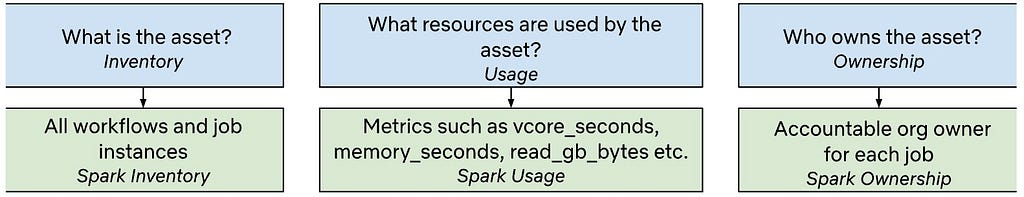
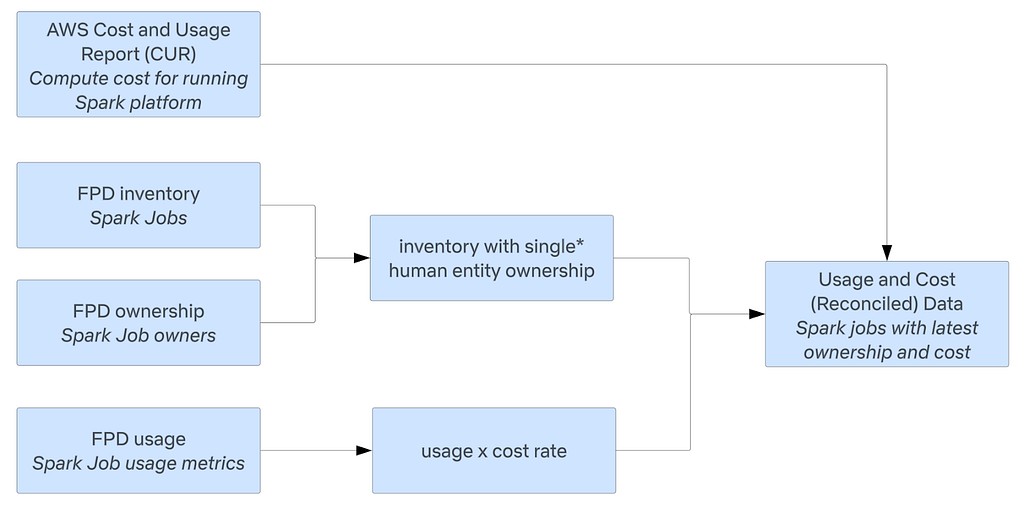
We work with different platform data providers to get inventory, ownership, and usage data for the respective platforms they own. Below is an example of how this framework applies to the Spark platform. FPD establishes data contracts with producers to ensure data quality and reliability; these contracts allow the team to leverage a common data model for ownership. The standardized data model and processing promotes scalability and consistency.

Cloud Efficiency Analytics (CEA Data)

Once the foundational data is ready, CEA consumes inventory, ownership, and usage data and applies the appropriate business logic to produce cost and ownership attribution at various granularities. The data model approach in CEA is to compartmentalize and be transparent; we want downstream consumers to understand why they’re seeing resources show up under their name/org and how those costs are calculated. Another benefit to this approach is the ability to pivot quickly as new or changes in business logic is/are introduced.

* For cost accounting purposes, we resolve assets to a single owner, or distribute costs when assets are multi-tenant. However, we do also provide usage and cost at different aggregations for different consumers.

Data Principles

As the source of truth for efficiency metrics, our team’s tenants are to provide accurate, reliable, and accessible data, comprehensive documentation to navigate the complexity of the efficiency space, and well-defined Service Level Agreements (SLAs) to set expectations with downstream consumers during delays, outages or changes.

While ownership and cost may seem straightforward, the complexity of the datasets is considerably high due to the breadth and scope of the business infrastructure and platform specific features. Services can have multiple owners, cost heuristics are unique to each platform, and the scale of infra data is large. As we work on expanding infrastructure coverage to all verticals of the business, we face a unique set of challenges:

A Few Sizes to Fit the Majority

Despite data contracts and a standardized data model on transforming upstream platform data into FPD and CEA, there is usually some degree of customization that is unique to that particular platform. As the centralized source of truth, we feel the constant tension of where to place the processing burden. Decision-making involves ongoing transparent conversations with both our data producers and consumers, frequent prioritization checks, and alignment with business needs as informed captains in this space.

Data Guarantees

For data correctness and trust, it’s crucial that we have audits and visibility into health metrics at each layer in the pipeline in order to investigate issues and root cause anomalies quickly. Maintaining data completeness while ensuring correctness becomes challenging due to upstream latency and required transformations to have the data ready for consumption. We continuously iterate our audits and incorporate feedback to refine and meet our SLAs.

Abstraction Layers

We value people over process, and it is not uncommon for engineering teams to build custom SaaS solutions for other parts of the organization. Although this fosters innovation and improves development velocity, it can create a bit of a conundrum when it comes to understanding and interpreting usage patterns and attributing cost in a way that makes sense to the business and end consumer. With clear inventory, ownership, and usage data from FPD, and precise attribution in the analytical layer, we aim to provide metrics to downstream users regardless of whether they utilize and build on top of internal platforms or on AWS resources directly.

Future Forward

Looking ahead, we aim to continue onboarding platforms to FPD and CEA, striving for nearly complete cost insight coverage in the upcoming year. Longer term, we plan to extend FPD to other areas of the business such as security and availability. We aim to move towards proactive approaches via predictive analytics and ML for optimizing usage and detecting anomalies in cost.

Ultimately, our goal is to enable our engineering organization to make efficiency-conscious decisions when building and maintaining the myriad of services that allow us to enjoy Netflix as a streaming service.

Acknowledgments

The FPD and CEA work would not have been possible without the cross functional input of many outstanding colleagues and our dedicated team building these important data assets.

—

A bit about the authors:

JHan enjoys nature, reading fantasy, and finding the best chocolate chip cookies and cinnamon rolls. She is adamant about writing the SQL select statement with leading commas.

Pallavi enjoys music, travel and watching astrophysics documentaries. With 15+ years working with data, she knows everything’s better with a dash of analytics and a cup of coffee!


Cloud Efficiency at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Turbocharging GrabUnlimited with Temporal

Post Syndicated from Grab Tech original https://engineering.grab.com/turbocharging-grabunlimited-with-temporal

Welcome to the behind-the-scenes story of GrabUnlimited, Grab’s flagship membership program. We undertook the mammoth task of migrating from our legacy system to a Temporal1 workflow-based system, enhancing our ability to handle millions of subscribers with increased efficiency and resilience. The result? A whopping 80% reduction in open production incidents, and most importantly – an improved membership experience for our users. In this first part of the series, you will learn how to design a robust and scalable membership system as we delve into our own experience building one.

What is GrabUnlimited?

The idea behind GrabUnlimited, is pretty simple: you pay a monthly fee, you get monthly benefits as a member (e.g discounted food delivery fee). A membership system plays a key role in enhancing user experience by giving them more value for money, but also by building loyalty, making Grab their go-to app for everyday needs. However, as this program grew and evolved, it brought along unique challenges and opportunities.

With the initial triumph and significant surge in subscriber count by over 1000% from January 2022 to June 2023 – which we were super proud of! – the architecture that supported GrabUnlimited was starting to show signs of strain. Common subscriber concerns such as not receiving their membership benefits, along with developer issues marked by an increase in service outages highlighted the system’s low resiliency. The culprit? A backend service that, while functional, was not built to efficiently manage the complexities of a rapidly scaling membership model.

Deep dive into our previous system design

As engineers, we know that deciding to migrate any system to a new one is like changing the engine of a running car. It requires meticulous evaluation of the existing systems, a deep dive into the issues and their root causes, and a thorough analysis of potential solutions and their trade-offs.

How was GrabUnlimited designed?

Initially, GrabUnlimited systems were designed for an experiment and not a full-fledged regional product. The idea was to try it out as a minimum viable product over a restricted segment of a few hundred thousand users. Let’s first have a look at how the membership program works.

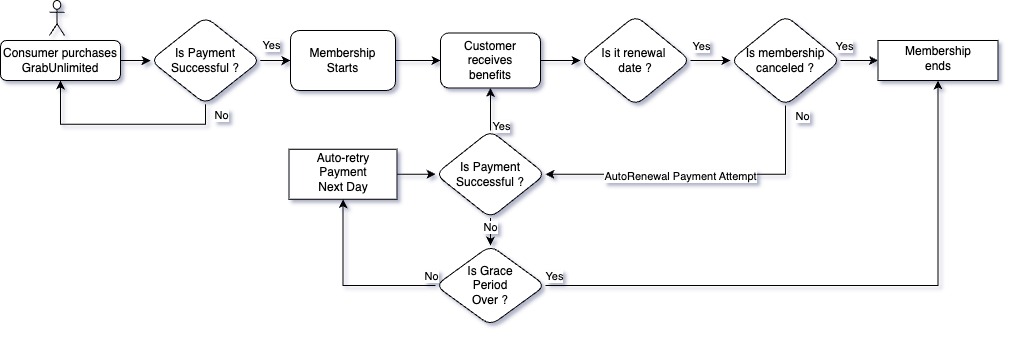
Figure 1. GrabUnlimited life of a membership flowchart.

Under the hood, our membership system relies on two main flows

  • Membership purchase: The user enrols for a certain duration (e.g 3 months), completes the payment through our Payment service, and receives benefits via our Reward service.
  • Membership renewal: A daily cron job2 checks which memberships need renewal, processes the payment, and delivers the benefits.

We employed a state machine3 approach to break down the membership process into smaller chunks called state handlers. For instance, a membership might transition through ‘Init’, ‘Charged’, ‘Rewarded’, and ‘Active’ states. To operate these states, we used Amazon’s Simple Queue Service (SQS). SQS acts as a manager, delegating state handlers to workers (our service) and monitoring the status of the state handler. If a worker fails to complete a task, SQS reassigns the task to another worker, ensuring no task is lost. The load is also spread across multiple workers, helping with scalability.

To safeguard our system against duplicate tasks such as charging the user twice, when a worker takes up a task, it would use a Redis lock4 mechanism with a time-to-live (TTL) of five minutes preventing any other worker from picking up the same task. If a worker fails or crashes, the lock expires and another worker can pick up the job.

So far, so good.

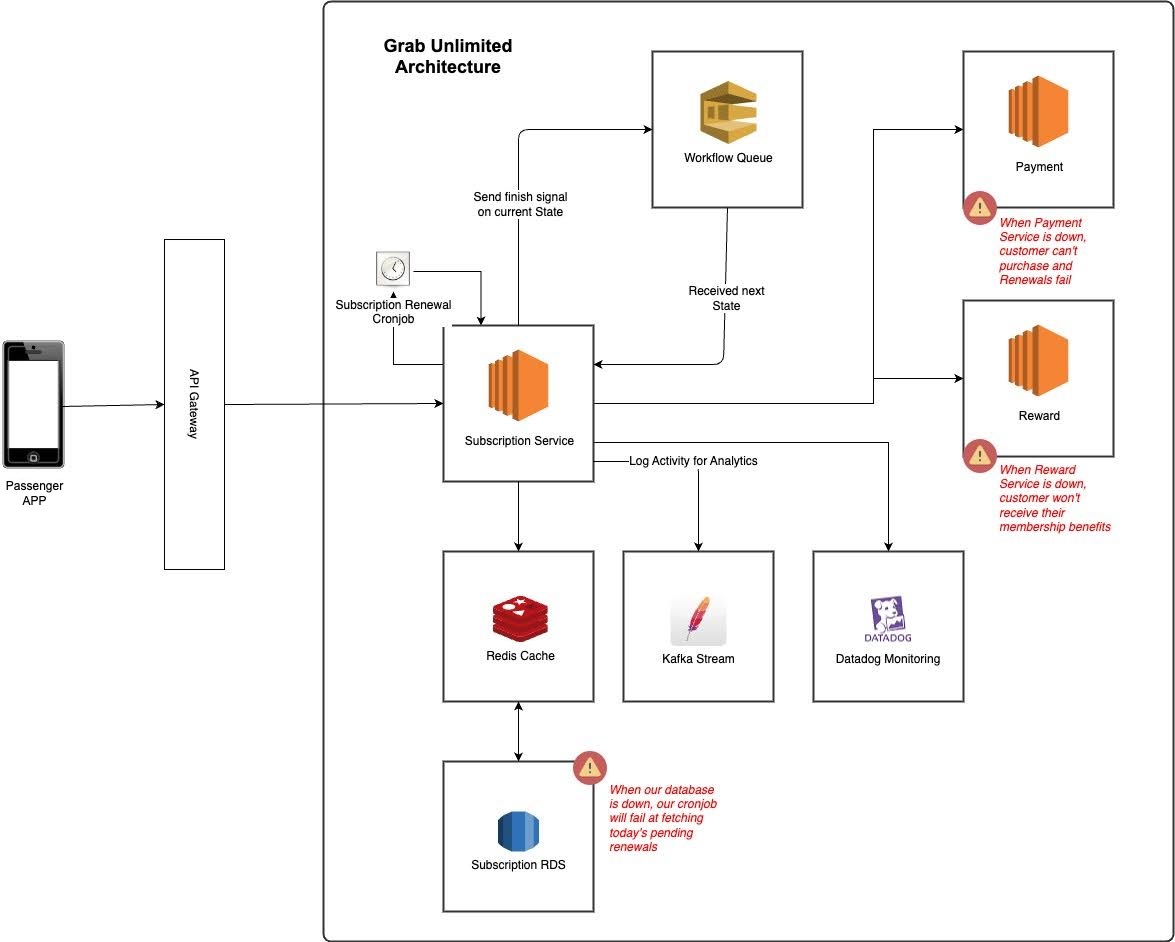
Figure 2. GrabUnlimited previous system design overview.

With our success came many challenges

As our subscriber base grew, we experienced an increase in system outages. To address this, we scrutinised metrics like the number of support tickets and gauged the toll on our engineering team. This included the time spent patching up issues and the opportunity cost of not developing new features or improvements.

From our subscribers’ point of view, we saw a steady increase in reported incidents.

  • Users were blocked because their membership status was corrupted in our database.
  • Memberships were not automatically renewed, or users were not able to resubscribe.
  • Users were not receiving their benefits after renewing their membership.

From the engineering team’s perspective, we were dedicating one engineer every week to battle these incidents full time. The on-call engineers were not only tasked with manually fixing all customer reports but were also swamped with frequent system alerts. This situation had three detrimental impacts on our team:

  • We were constantly putting out fires instead of addressing the root causes.
  • We were spending resources that could have been used to enhance our customers’ experience.
  • Our team’s motivation and confidence was taking a big hit.

Finding the architectural culprit

The first step was to clearly identify and understand the issues within our systems. We looked at the frequency of failures and their root cause. From there, we were able to detect recurring patterns, which led us to four major issues in our architecture.

Scalability

Our system’s cron job, which retrieves all daily memberships due for renewal from our database, becomes slower and more resource-intensive as the number of members increases. Despite our attempt to alleviate high database usage by dividing the process into multiple batches and running several cron jobs, we were still experiencing significant surges each time a cron job runs. So our only viable solution was vertical scaling5 of the database. In other words, we had a serious bottleneck in our system.

Figure 3. Database queries per second during membership renewals at night.

Concurrency6

Picture this – A user tries to cancel their membership in the middle of the auto-renewal process, and voila, we have what we call a “zombie” state where the membership is both cancelled and renewed. This situation happens due to the limitations of our 5-minute Redis lock. If the renewal process holding the lock doesn’t complete within the timeout, the lock is released, enabling the cancel process to obtain the lock and run concurrently.

Resiliency7

What happens when the Rewards service faces an outage? The user buys a membership but doesn’t receive the rewards. It’s like throwing a party but the guests never arrive. We had three issues here:

  • In the event where upstream services had an outage, we relied on SQS’s maximum number of retries without exponential backoff8, causing potential overloads on recovering services.
  • Our cron job being housed within the service itself was susceptible to interruptions during outages or service restarts.
  • Over time, the logic to transition between states in our state machine became complex and multi-responsibility as more states were added. This made our retry mechanism unreliable due to potential risks of double charging or double awarding users. Which leads us to our fourth culprit.

Idempotency9

Even when some steps could be retried, our system lacked idempotency guarantees – a safety net to ensure that a step could be repeated without unintended side effects. Although our critical upstream systems like Payments and Rewards support idempotency via idempotency keys, our service wasn’t originally designed with this in mind.

  • Users could be stuck in a state where the payment succeeded but they didn’t receive their benefits or received them twice, requiring manual intervention from engineers.
  • We were not able to auto-retry membership renewals if the cron job, database, or any service had an outage.
Figure 4. Example of Idempotency issue in our old system design. If a single task fails in a state handler, the whole step would be retried which could lead to a double awarding.

For example, consider a state handler “BenefitsAwarding” that follows these steps:

  1. Generate an idempotency key.
  2. Calls Reward service to award the first set of benefits to the subscriber using the key.
  3. Calls Reward service to award the second set of benefits to the subscriber using the key.

If step 3 fails due to an outage, and the step is retried and re-queued in SQS, it would restart from step 1. This generates a new idempotency key, meaning the Reward system wouldn’t recognize the retry and will award Benefits1 twice. One way to fix this with our current design is to substantially increase the number of states in our SQS state machine, to isolate tasks further rather than handling too much logic in a state handler. However, that would mean having hundreds of states making the whole process difficult to maintain.

Ultimately, most incidents traced back to one fundamental issue: Our systems were relying on a sequential process that couldn’t be easily replayed if any incident or disturbance happened during execution. We were placing all our bets on the happy path, a risky gamble indeed.

The Solution: Migrating our system to Temporal

Armed with a clear understanding of the problems and their impacts, we set out to explore potential solutions. This journey led us to consider refactoring our existing system or migrating to a new architecture that another team introduced to us: Temporal.

Enter Temporal

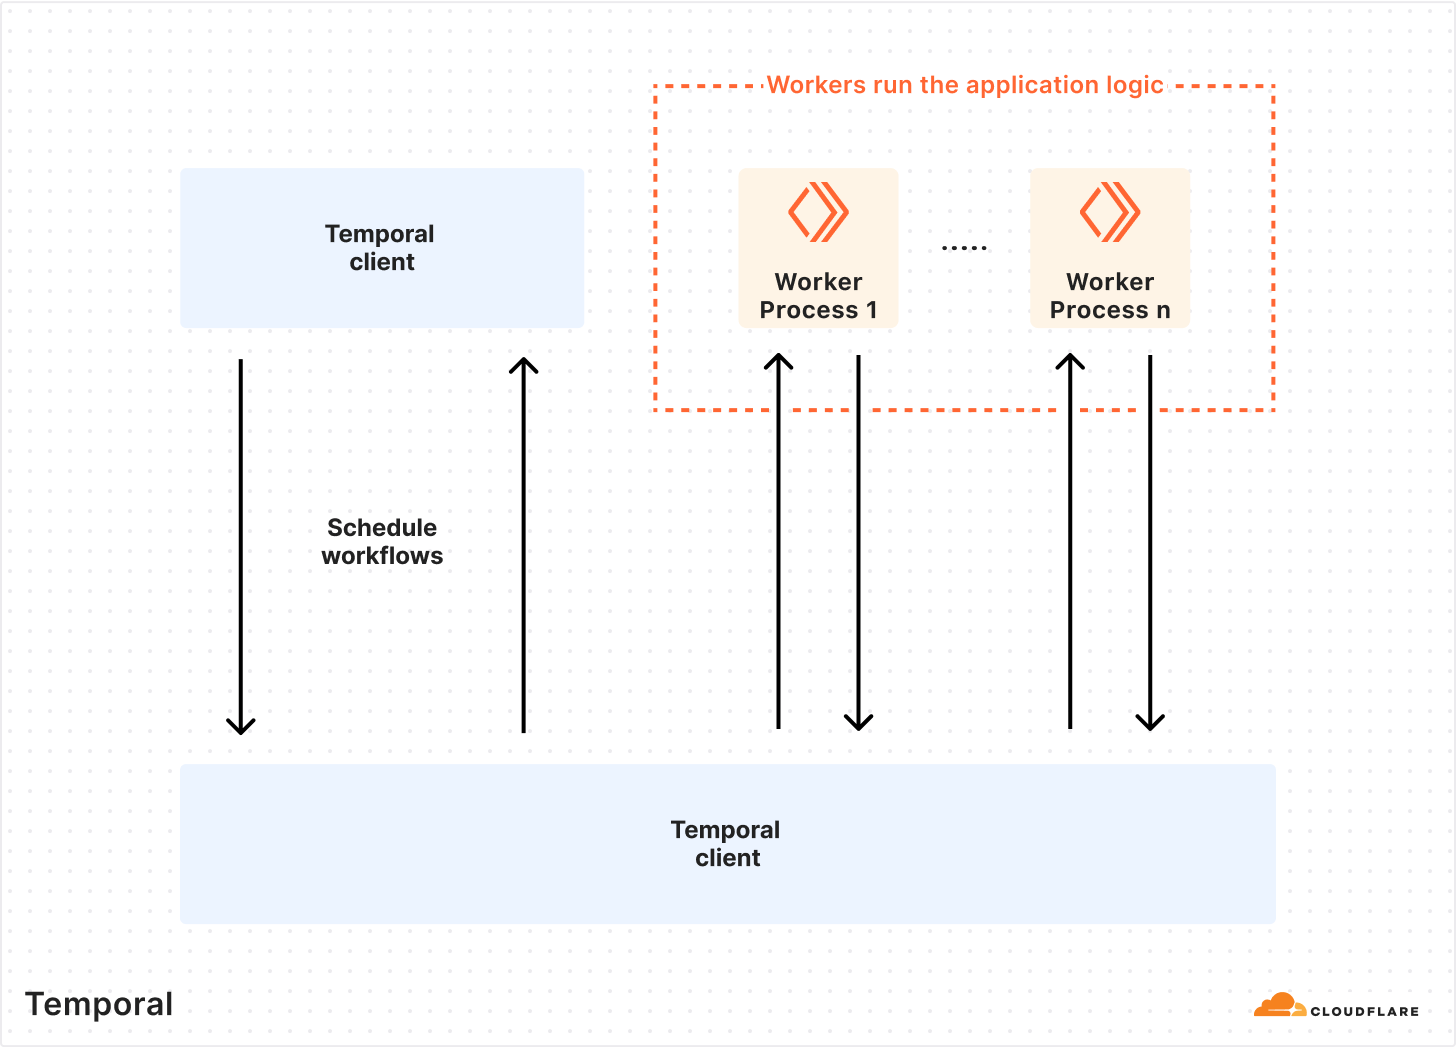
Temporal is an open-source workflow orchestration engine. Think of it as a more robust and battle-tested implementation of our previous SQS architecture. It’s designed to run millions of workflows concurrently and can recover/resume the state of a workflow execution at the exact point of failure even in the event of an outage. It has features like infinite retries, exponential backoff, rate limiting, and observability out of the box. This sounded exactly like what we needed! By using Temporal, we could offload the complexity of managing state transitions, retries, and task concurrency, allowing us to focus on our core business logic.

In order to make the right decision, we meticulously assessed our options over the following criteria: scalability10, reliability11, resiliency12, performance, development effort, cost, security, flexibility13, and testability14. We realised that most of what we needed to build to compensate for our system design gaps was already built into Temporal. Let’s have a sneak peek on how the architecture looks and how it solves all four major culprits we discussed.

Figure 5. GrabUnlimited new system design architecture.

Fixing our architecture culprits

Scalability

Let’s start with the easiest fix, remember our old cron job for membership renewals? We replaced it with Timer which allows a workflow to sleep and automatically wake up. Instead of renewing membership by batches, they are now renewed throughout the entire day based on the hour and minute when the user subscribed. What does this mean for us? We no longer need to fetch memberships from our database to trigger renewals. The workflow will resume at the due date to process the renewal, eliminating the database as a bottleneck.

Figure 6. Total queries per second (QPS) on database before and after the migration to Temporal.

Concurrency

Our legacy Redis lock mechanism was clearly not enough. However, with Temporal, we have alternative solutions to avoid race conditions. What happens if a user tries to cancel while the membership renewal workflow is being triggered? Temporal allows us to assign the same workflow ID to multiple workflows running mutually exclusive operations, ensuring only one operation runs at a time. Basically, we assigned the same workflow ID to both cancellation and renewal workflows, either cancellation happens first, removing the need to renew the consumer membership, or renewal takes the lead, and cancellation only happens after.

Figure 7. Total corrupted membership states (zombies) manually handled by engineers significantly decreased during our migration which started in February.

Resiliency

Out of the box, Temporal allowed us to put in place a few key resilience mechanisms like exponential backoff and infinite retry which was a key gap in our previous SQS architecture. That was great because we didn’t have to implement these mechanisms on our own and it meant that when calling key upstream services like Payment, we were able to precisely set our retry policies without overwhelming the service in case of an outage on their end.

Idempotency

Remember our fourth culprit from above? Our state handlers with SQS were performing too many tasks simultaneously, which made it risky to trust the retry process. This multi-responsibility nature introduced significant risks, including potential database corruption, double charging, and double awarding of benefits. Further breaking down these steps would result in hundreds of intermediary steps, each requiring careful maintenance and correct sequencing. With Temporal, you can imagine a membership as an ever-running workflow consisting of a sequence of steps that are automatically managed and retried in case of failures.

While this approach didn’t directly resolve idempotency issues, it made the system and the code more readable and allowed us to design steps with single responsibilities. This, in turn, made it simpler for us to develop and ensure these steps were idempotent.

Let’s take a look at our previous example with Temporal.

Figure 8. Temporal workflow: If a single task fails, only that task is retried.

Let’s consider the same use case where a member needs to receive their benefits. The tasks remain the same except we don’t need to persist the idempotency key as it will be in the Temporal workflow state instead.

  1. Generate idempotency keys.
  2. Calls Reward service to award the first set of benefits to the subscriber using the key abc1.
  3. Calls Reward service to award the second set of benefits to the subscriber using the second key xyz1.

If the “AssignBenefits2” step fails, and the process is retried by Temporal, it will restart directly from that step, thus preventing the double awarding we were experiencing with SQS. Thanks to this approach, we largely improved idempotency and resiliency in our system, which also led to great results in decreasing user reported incidents.

Figure 9. Total open production incidents reported by users related to membership issues from January to October 2024.

Embracing Temporal: Challenges and mindset shift

Transitioning to Temporal was quite a paradigm shift for our team. Rather than managing SQS state transitions, we could now focus on our core business logic while Temporal handled the complexities of state management, error handling, and retries. This change allowed us to streamline development, making our processes more intuitive.

However, this shift wasn’t without its challenges. Temporal features such as Workflow and Activity design, deterministic execution, and built-in retry mechanisms required a steep learning curve. We had to quickly adapt to Temporal’s new way of thinking, and while it took some time to master these tools, they ultimately led to a more robust and scalable system. The transition to Temporal brought not only technical improvements but also a new mindset for solving problems efficiently.

Key takeaways and conclusion

After a thorough analysis, we decided to transition our architecture to Temporal, as it outperformed on nearly every evaluation criteria. Here are the key takeaways from our experience:

  • Understand the problem, fix it for the future: Migrating legacy systems requires more than just patching up issues; it demands a deep dive into the root causes. For us, that meant addressing challenges in scalability, resiliency, and concurrency head-on to prevent future headaches.
  • Focusing on what matters: By adopting Temporal workflow orchestration, we could shift our focus to what really counts, core business logic. The result? An 80% reduction in production incidents and a much smoother post-migration experience.
  • Resilience and flexibility at scale: Temporal provided the infrastructure we needed to handle millions of subscribers with more robust processes for retries, idempotency, and state management. These features played a key role in ensuring the system remained stable and flexible as our user base grew.
  • The learning curve pays off: Every system migration has its challenges, but the payoff was transformative. Despite the initial hiccups, moving to Temporal allowed us to scale GrabUnlimited seamlessly while significantly improving both our development processes and the overall user experience.

Stay tuned for Part 2, where we dive into the challenges of the migration and the lessons learned along the way. How did we seamlessly migrate millions of users to this new architecture without disrupting their memberships? How did we implement Temporal without pausing development for months? And what roadblocks did we encounter as we scaled this solution to all our users? We’ll answer these questions and more in the next post.

Nothing would have been possible without the unwavering support of Abegail Nato Alcantara, Andrys Silalahi, Pavel Sidlo, and Renu Yadav.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Definition of terms

  1. Temporal: Temporal is an open-source workflow orchestration platform. It allows developers to build scalable and reliable applications using familiar development patterns and easy-to-use tools. ↩

  2. Cron job: A cron job is a time-based job scheduler in Unix-like operating systems. Users can schedule jobs (commands or scripts) to run periodically at fixed times, dates, or intervals. ↩

  3. State machine: A state machine is a behavioural model used in computer science. It represents a system in terms of states and transitions between those states. ↩

  4. Redis lock mechanism: Redis is an in-memory data structure store that can be used as a database, cache, and message broker. A Redis lock mechanism is a way to ensure that only one computer in a distributed network can process a certain piece of code at a time. ↩

  5. Vertical scaling: also known as “scaling up”, is the process of adding more resources (such as memory, CPUs, or storage) to an existing server or database to enhance its performance and capacity. Which is different from Horizontal scaling, also known as “scaling out”, the process of adding more servers or nodes to a system to handle increased load. ↩

  6. Concurrency: In computing, concurrency is the ability of different parts or units of a program, algorithm, or problem to be executed out-of-order or in partial order, without affecting the final outcome. ↩

  7. Resiliency: refers to the ability of a system or application to quickly recover from failures and continue its intended operation without significant interruption. ↩

  8. Exponential backoff: Exponential backoff is an algorithm that uses feedback to multiplicatively decrease the rate of some process, in order to gradually find an acceptable rate. In the context of the article, it refers to a strategy for retrying failed tasks with increasing wait times between retries. ↩

  9. Idempotency: An operation is idempotent if the result of performing it once is exactly the same as the result of performing it repeatedly without any intervening actions. ↩

  10. Scalability: The ability of a system to handle increased workload or demand by adding resources. ↩

  11. Reliability: The capacity of a system to consistently perform its intended functions without failure. ↩

  12. Resiliency: The ability of a system to recover quickly and effectively from failures or disruptions, ensuring continuity of service. ↩

  13. Flexibility: The architecture should be flexible enough to accommodate future changes in requirements. ↩

  14. Testability: The architecture should allow for effective testing to ensure the system works as expected. ↩

How we seamlessly migrated high volume real-time streaming traffic from one service to another with zero data loss and duplication

Post Syndicated from Grab Tech original https://engineering.grab.com/seamless-migration

At Grab, we continuously enhance our systems to improve scalability, reliability and cost-efficiency. Recently, we undertook a project to split the read and write functionalities of one of our backend services into separate services. This was motivated by the need to independently scale these operations based on their distinct scalability requirements.

In this post, we will dive deep into how we migrated the stream processing (write) functionality to a new service with zero data loss and duplication. This was accomplished while handling a high volume of real-time traffic averaging 20,000 reads per second from 16 source Kafka streams writing to other output streams and several DynamoDB tables.

Migration challenges and strategy

Migrating the stream processing to the new service while ensuring zero data loss and duplication posed some interesting challenges, especially given the high volume of real-time data. We needed a strategy that would enable us to:

  • Migrate streams one by one gradually.
  • Validate the new service’s processing in production before fully switching over.
  • Perform the switchover with no downtime or data inconsistencies.

We considered various options for the switchover such as using feature flags via our unified config management and experimental rollout platform. However, these approaches had some limitations:

  • There could be some data loss or duplication during the deployment time when toggling the flags, which can be up to a few minutes.
  • There might be data inconsistencies as the flag value could be updated on the services (the existing and and the new one) at slightly different times.

Ultimately, we decided on a custom time-based switchover logic implemented in shared code between the two services leveraging our monorepo structure. In the following sections, we will walk you through the steps we took to achieve this seamless migration.

Step 1: Preparation

First, since both the existing and new services reside in our monorepo, we moved the stream processing code from the existing service to a shared /commons directory. This allowed both the old and new services to import and use the same code. We added logic in this commons package to selectively turn stream processing on or off based on the service processing them.

Next, we created temporary “sink” resources such as streams and DynamoDB tables for the new service to write the processed data. This allowed us to monitor and validate the new service’s behavior in production without impacting the main resources.

Figure 1. For a short period, both services consumed the incoming streams, but only the old service continued to write to the actual sink resources while the new service wrote to validation sink resources.

Step 2: Scheduling the switchover

In the shared /commons code, we added a map[string]time.Time to schedule the switchover for each stream.

map[string]time.Time{
  "streamA": time.Date(2024, 2, 28, 12, 0, 0, 0, time.UTC),
  "streamB": time.Date(2024, 3, 10, 12, 0, 0, 0, time.UTC),
  // ...
}

When a stream is added to this map, it means it is scheduled for switchover at the specified time. This logic is shared between both services, so the switchover happens simultaneously. The new service starts writing to the main resources while the old service stops, with no overlap or gap.

Step 3: Deployment and monitoring

To perform the switchover, we:

  1. Updated the switchover times for the streams.
  2. Deployed both services with enough buffer time before the scheduled switch.
  3. Closely monitored the process by creating dedicated monitors for the migration process using our observability tools.
Figure 2. This timeseries graph shows the stream received at the old and the new service (dotted line), facilitating real time monitoring of the stream processing volume across both services during the validation period.

The old service continued consuming the streams for a short monitoring period post-switchover, but without writing anywhere, ensuring no loss or duplication at the output sink resources. Then, the stream consumption was removed from the old service altogether, completing the entire migration process.

Results and learnings

Using this time-based approach, we were able to seamlessly migrate the high-volume stream processing to the new service with:

  • Zero data loss or duplication.
  • No downtime or production issues.

The whole migration, including the gradual stream-by-stream switchover, was completed in about three weeks.

One learning was that such custom time-based logic, while effective for our use case, has limitations. If a rollback was needed for any of the two services for some unexpected reasons, some data inconsistency would be unavoidable. Generally, such time-based logic should be used with caution as it can lead to unexpected scenarios if the systems fall out of sync. We went ahead with this approach as it was a temporary measure and we had thoroughly tested it before carrying out the switchover.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Supercharging LLM Application Development with LLM-Kit

Post Syndicated from Grab Tech original https://engineering.grab.com/supercharging-llm-application-development-with-llm-kit

Introduction

At Grab, we are committed to leveraging the power of technology to deliver the best services to our users and partners. As part of this commitment, we have developed the LLM-Kit, a comprehensive framework designed to supercharge the setup of production-ready Generative AI applications. This blog post will delve into the features of the LLM-Kit, the problems it solves, and the value it brings to our organisation.

Challenges

The introduction of the LLM-Kit has significantly addressed the challenges encountered in LLM application development. The involvement of sensitive data in AI applications necessitates that security remains a top priority, ensuring data safety is not compromised during AI application development.

Concerns such as scalability, integration, monitoring, and standardisation are common issues that any organisation will face in their LLM and AI development efforts.

The LLM-Kit has empowered Grab to pursue LLM application development and the rollout of Generative AI efficiently and effectively in the long term.

Introducing the LLM-Kit

The LLM-Kit is our solution to these challenges. Since the introduction of the LLM Kit, it has helped onboard hundreds of GenAI applications at Grab and has become the de facto choice for developers. It is a comprehensive framework designed to supercharge the setup of production-ready LLM applications. The LLM-Kit provides:

  • Pre-configured structure: The LLM-Kit comes with a pre-configured structure containing an API server, configuration management, a sample LLM Agent, and tests.
  • Integrated tech stack: The LLM-Kit integrates with Poetry, Gunicorn, FastAPI, LangChain, LangSmith, Hashicorp Vault, Amazon EKS, and Gitlab CI pipelines to provide a robust and end-to-end tech stack for LLM application development.
  • Observability: The LLM-Kit features built-in observability with Datadog integration and LangSmith, enabling real-time monitoring of LLM applications.
  • Config & secret management: The LLM-Kit utilises Python’s configparser and Vault for efficient configuration and secret management.
  • Authentication: The LLM-Kit provides built-in OpenID Connect (OIDC) auth helpers for authentication to Grab’s internal services.
  • API documentation: The LLM-Kit features comprehensive API documentation using Swagger and Redoc.
  • Redis & vector databases integration: The LLM-Kit integrates with Redis and Vector databases for efficient data storage and retrieval.
  • Deployment pipeline: The LLM-Kit provides a deployment pipeline for staging and production environments.
  • Evaluations: The LLM-Kit seamlessly integrates with LangSmith, utilising its robust evaluations framework to ensure the quality and performance of the LLM applications.

In addition to these features, the team has also included a cookbook with many commonly used examples within the organisation providing a valuable resource for developers. Our cookbook includes a diverse range of examples, such as persistent memory agents, Slackbot LLM agents, image analysers and full-stack chatbots with user interfaces, showcasing the versatility of the LLM-Kit.

The value of the LLM-Kit

The LLM-Kit brings significant value to our teams at Grab:

  • Increased development velocity: By providing a pre-configured structure and integrated tech stack, the LLM-Kit accelerates the development of LLM applications.
  • Improved observability: With built-in LangSmith and Datadog integration, teams can monitor their LLM applications in real-time, enabling faster issue detection and resolution.
  • Enhanced security: The LLM-Kit’s built-in OIDC auth helpers and secret management using Vault ensure the secure development and deployment of LLM applications.
  • Efficient data management: The integration with Vector databases facilitates efficient data storage and retrieval, crucial for the performance of LLM applications.
  • Standardisation: The LLM-Kit provides a paved-road framework for building LLM applications, promoting best practices and standardisation across teams.

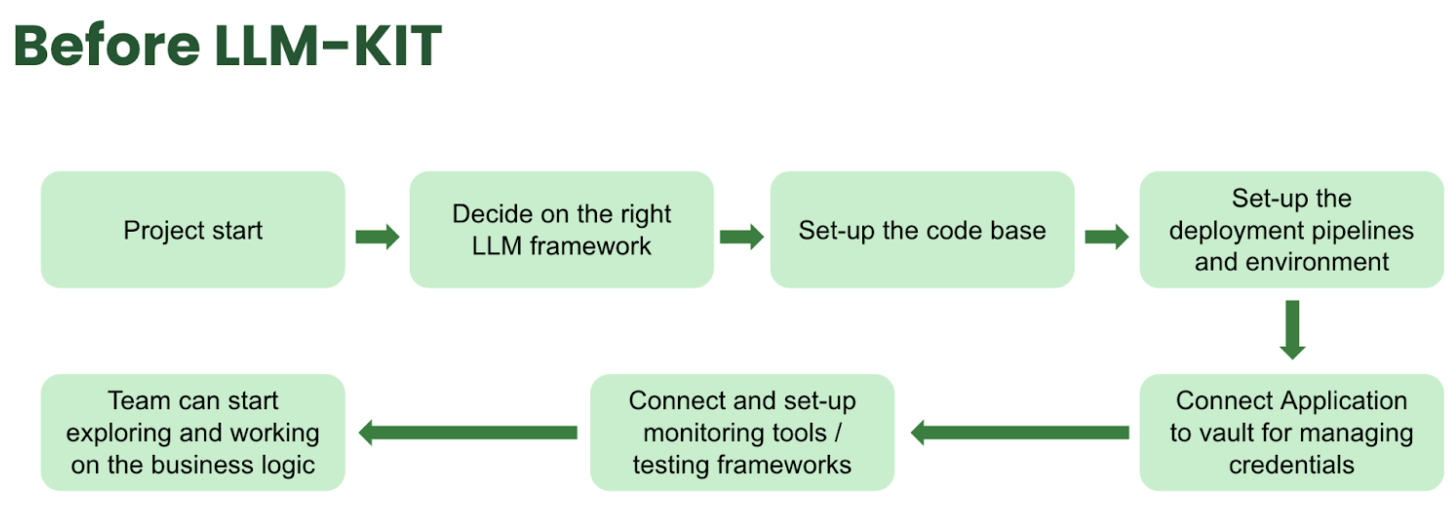
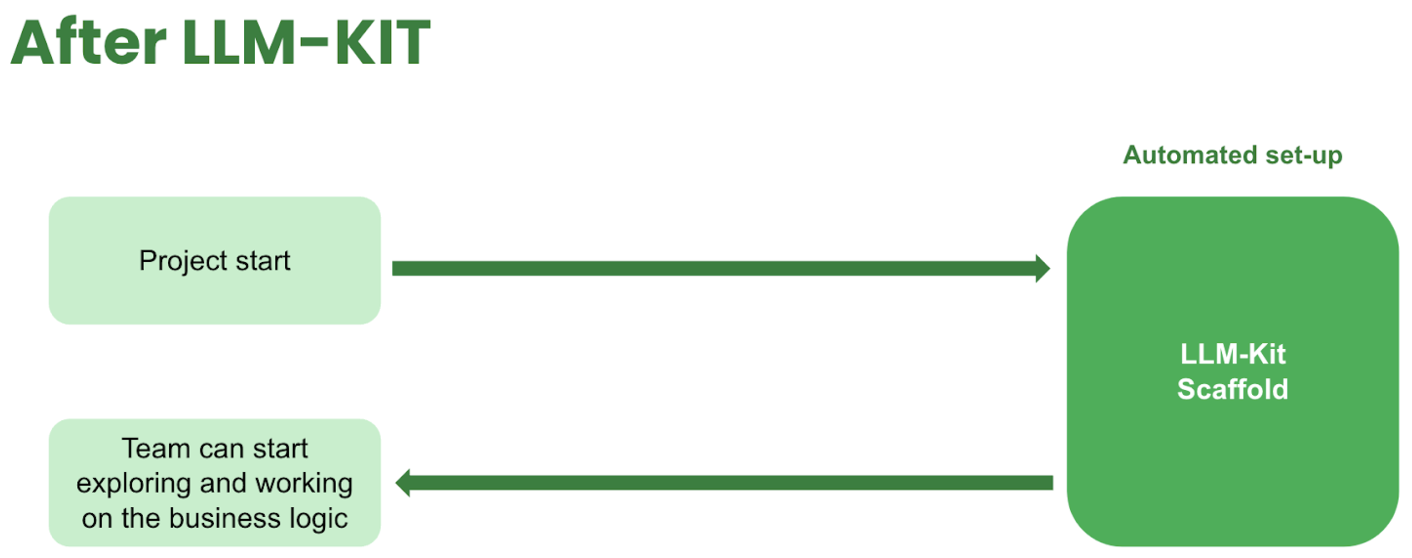
Through the LLM-Kit, we can save an estimate of 1.5 weeks before teams start working on their first feature.

Figure 1. Project development process before LLM-Kit
Figure 2. Project development process after LLM-Kit

Architecture design and technical implementation

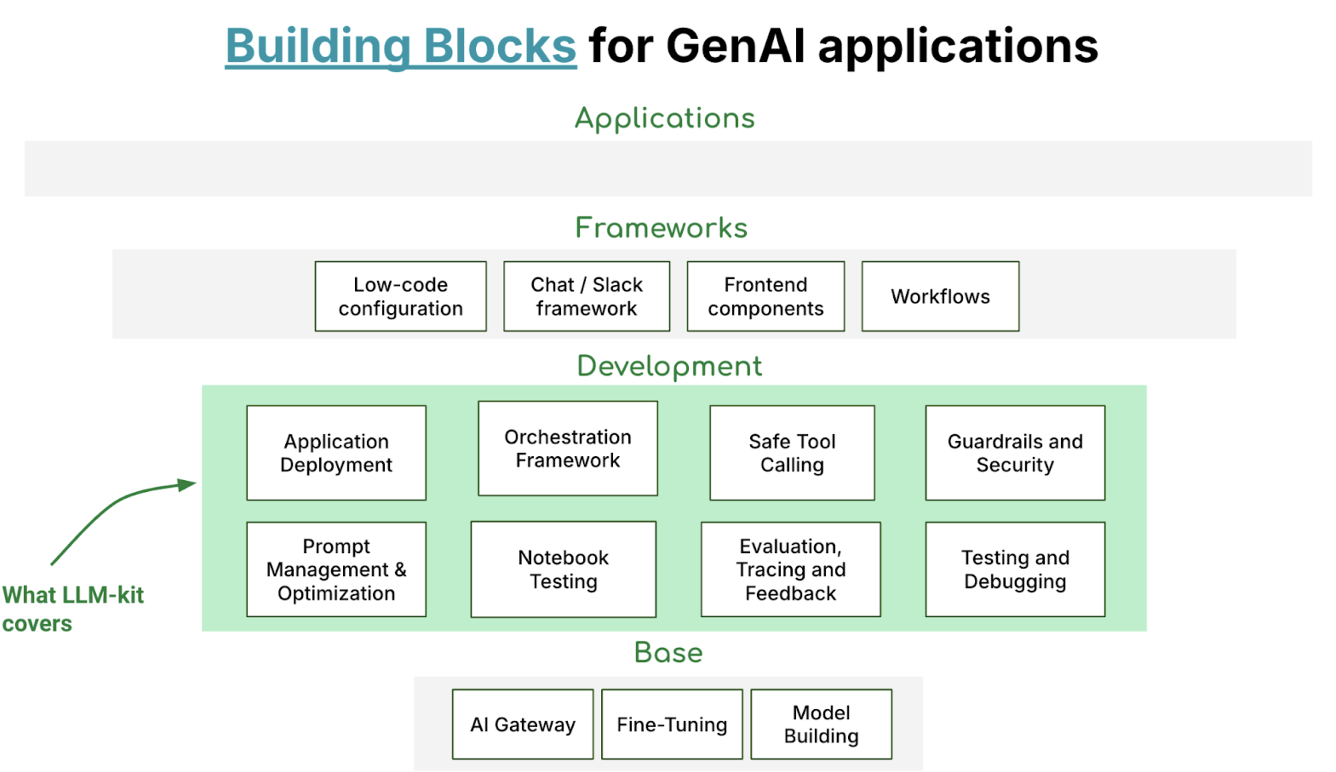
The LLM-Kit is designed with a modular architecture that promotes scalability, flexibility, and ease of use.

Figure 3. LLM-Kit modules

Automated steps

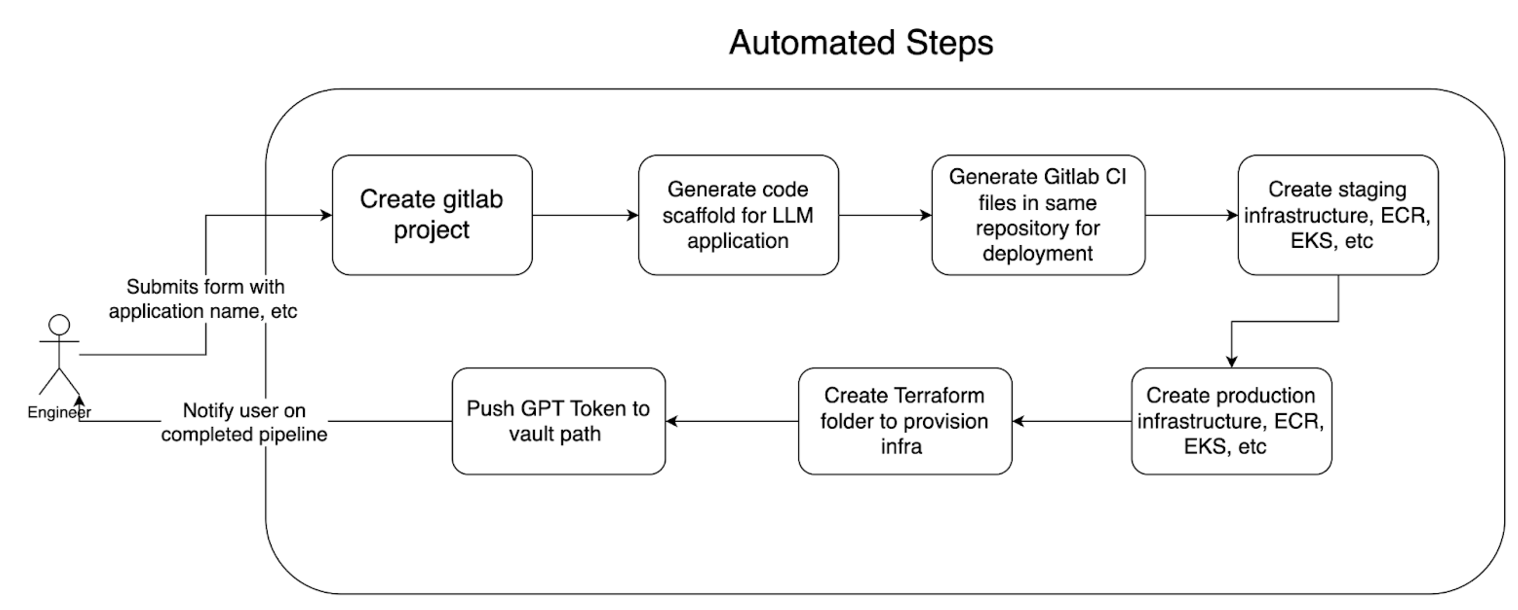
To better illustrate the technical implementation of the LLM-Kit, let’s take a look at figure 4 which outlines the step-by-step process of how an LLM application is generated with the LLM-Kit:

Figure 4. Process of generating LLM apps using LLM-Kit

The process begins when an engineer submits a form with the application name and other relevant details. This triggers the creation of a GitLab project, followed by the generation of a code scaffold specifically designed for the LLM application. GitLab CI files are then generated within the same repository to handle continuous integration and deployment tasks. The process continues with the creation of staging infrastructure, including components like Elastic Container Registry (ECR) and Elastic Kubernetes Service (EKS). Additionally, a Terraform folder is created to provision the necessary infrastructure, eventually leading to the deployment of production infrastructure. At the end of the pipeline, a GPT token is pushed to a secure Vault path, and the engineer is notified upon the successful completion of the pipeline.

Scaffold code structure

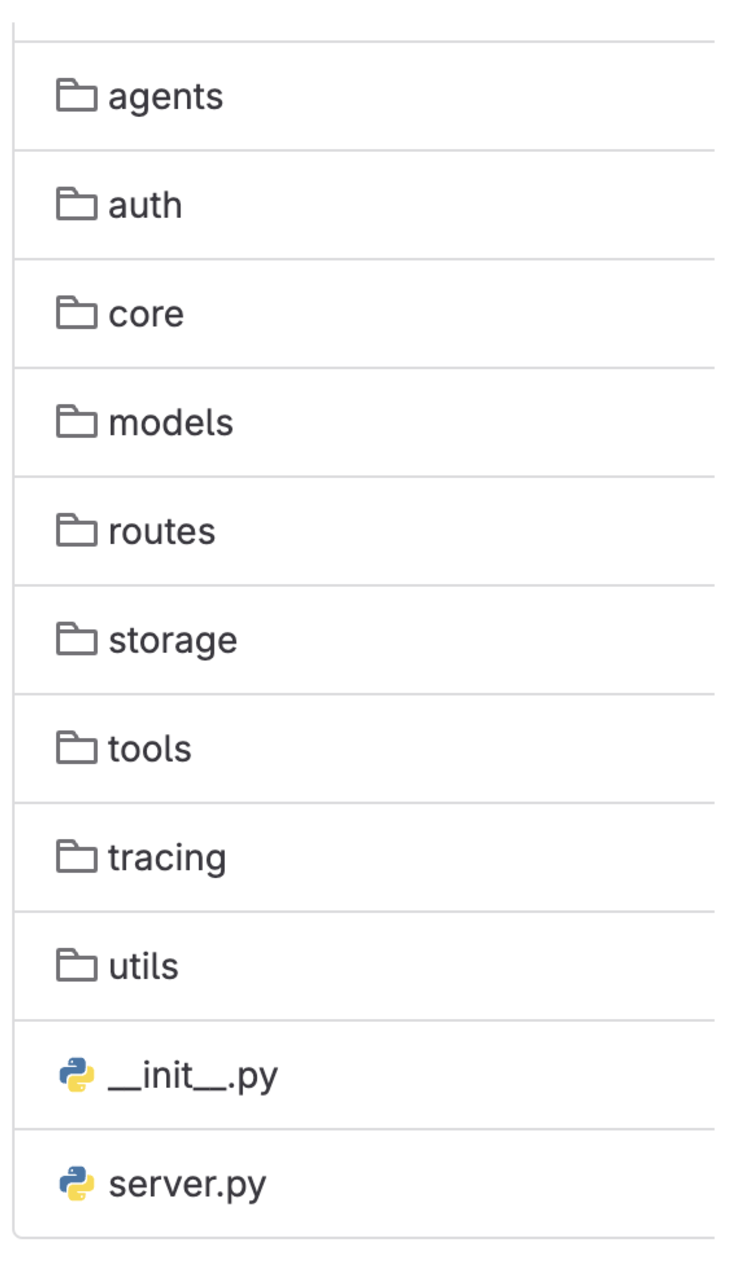
The scaffolded code is broken down into multiple folders:

  1. Agents: Contains the code to initialise an agent. We have gone ahead with LangChain as the agent framework; essentially the entry point for the endpoint defined in the Routes folder.
  2. Auth: Authentication and authorisation module for executing some of the APIs within Grab.
  3. Core: Includes extracting all configurations (i.e. GPT token) and secret decryption for running the LLM application.
  4. Models: Used to define the structure for the core LLM APIs within Grab.
  5. Routes: REST API endpoint definitions for the LLM Applications. It comes with health check, authentication, authorisation, and a simple agent by default.
  6. Storage: Includes connectivity with PGVector, our managed vector database within Grab and database schemas.
  7. Tools: Functions which are used as tools for the LLM Agent.
  8. Tracing: Integration with our tracing and monitoring tools to monitor various metrics for a production application.
  9. Utils: Default folder for utility functions.
Figure 5. Scaffold code structure

Infrastructure provisioning and deployment

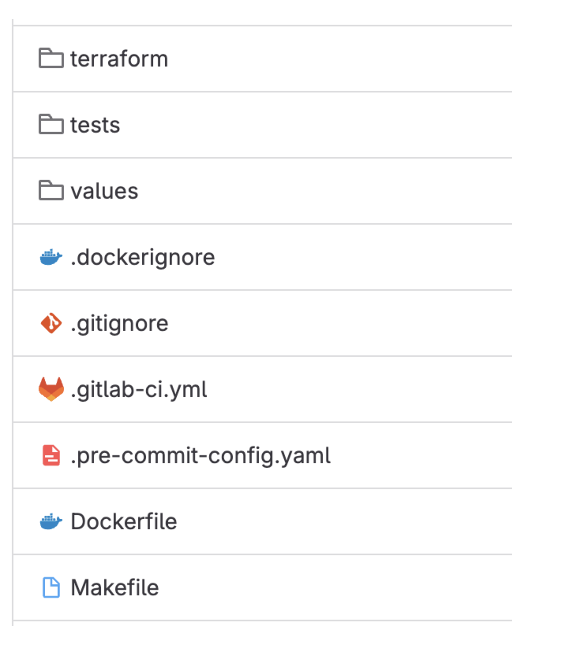
Within the same codebase, we have integrated a comprehensive pipeline that automatically scaffolds the necessary code for infrastructure provisioning, deployment, and build processes. Using Terraform, the pipeline provisions the required infrastructure seamlessly. The deployment pipelines are defined in the .gitlab-ci.yml file, ensuring smooth and automated deployments. Additionally, the build process is specified in the Dockerfile, allowing for consistent builds. This automated scaffolding streamlines the development workflow, enabling developers to focus on writing business logic without worrying about the underlying infrastructure and deployment complexities.

Figure 6. Pipeline infrastructure

RAG scaffolding

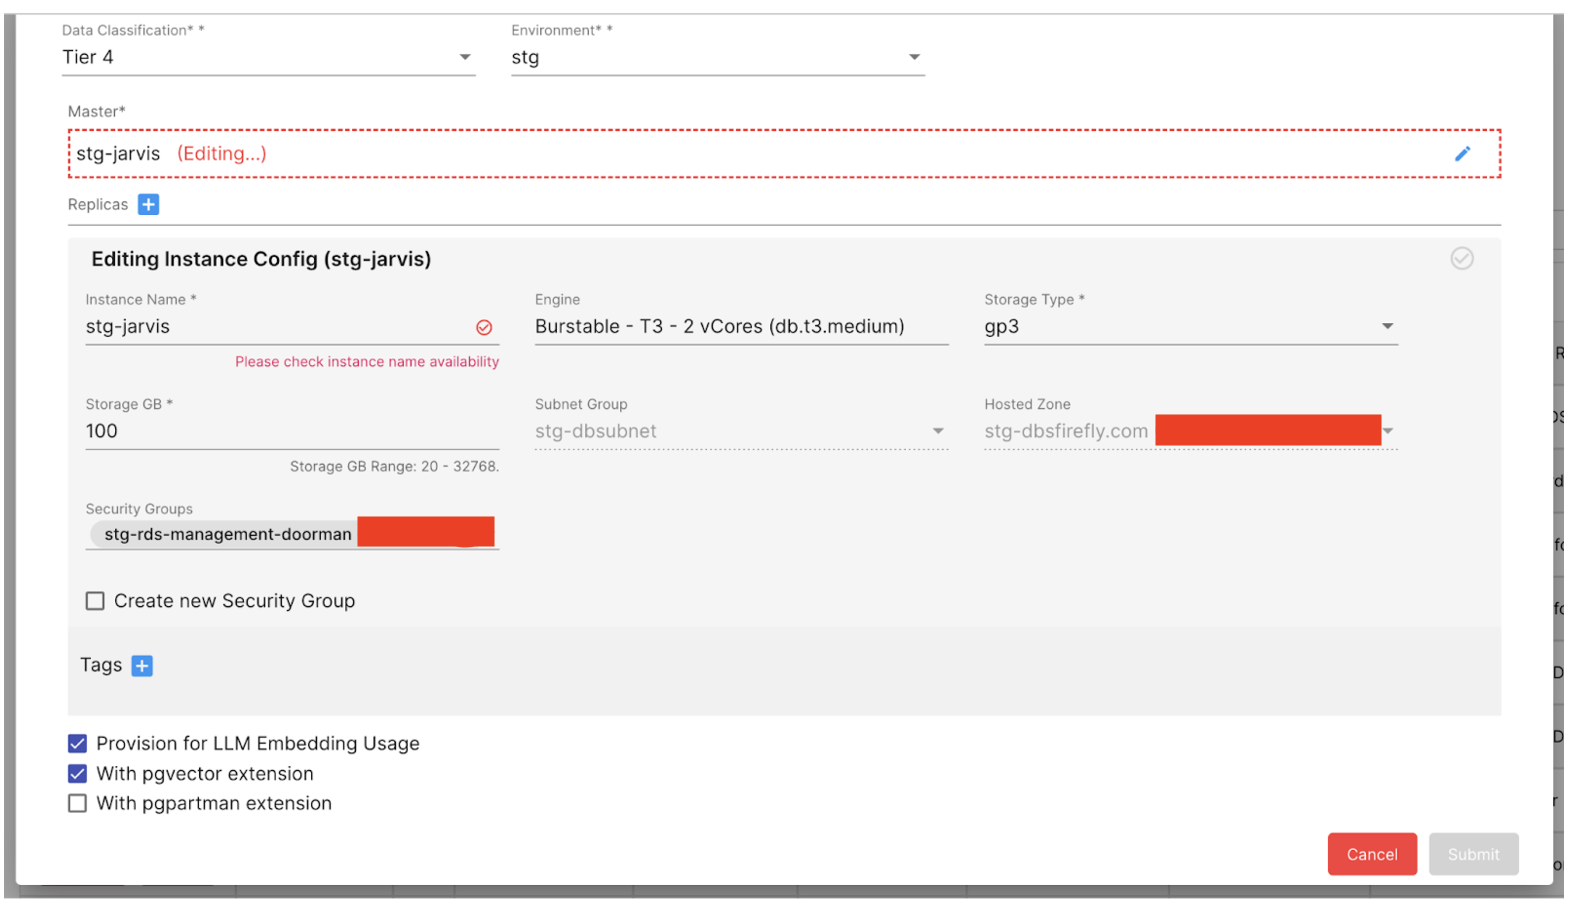
At Grab, we’ve established a streamlined process for setting up a vector database (PGVector) and whitelisting the service using the LLM-Kit. Once the form (figure 7) is submitted, you can access the credentials and database host path. The secrets will be automatically added to the Vault path. Engineers will then only need to include the DB host path in the configuration file of the scaffolded LLM-Kit application.

Figure 7. Form submitted to access credentials and database host path

Conclusion

The LLM-Kit is a testament to Grab’s commitment to fostering innovation and growth in AI and ML. By addressing the challenges faced by our teams and providing a comprehensive, scalable, and flexible framework for LLM application development, the LLM-Kit is paving the way for the next generation of AI applications at Grab.

Growth and future plans

Looking ahead, the LLM-Kit team aims to significantly enhance the web server’s concurrency and scalability while providing reliable and easy-to-use SDKs. The team plans to offer reusable and composable LLM SDKs, including evaluation and guardrails frameworks, to enable service owners to build feature-rich Generative AI programs with ease. Key initiatives also include the development of a CLI for version updates and dev tooling, as well as a polling-based agent serving function. These advancements are designed to drive innovation and efficiency within the organisation, ultimately providing a more seamless and efficient development experience for engineers.

We would like to acknowledge and thank Pak Zan Tan, Han Su, and Jonathan Ku from the Yoshi team and Chen Fei Lee from the MEKS team for their contribution to this project under the leadership of Padarn George Wilson.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Breaking down CPU speed: How utilization impacts performance

Post Syndicated from Andreas Strikos original https://github.blog/engineering/architecture-optimization/breaking-down-cpu-speed-how-utilization-impacts-performance/


Introduction ⛵

The GitHub Performance Engineering team regularly conducts experiments to observe how our systems perform under varying load conditions. A consistent pattern in these experiments is the significant impact of CPU utilization on system performance. We’ve observed that as CPU utilization rises, it can lead to increased latency, which provides an opportunity to optimize system efficiency. Addressing this challenge allows us to maintain performance levels while reducing the need for additional machines, ultimately preventing inefficiencies.

Although we recognized the correlation between higher CPU utilization and increased latency, we saw an opportunity to explore the specific thresholds and impacts at various stages in greater detail. With a diverse set of instance types powered by different CPU families, we focused on understanding the unique performance characteristics of each CPU model. This deeper insight empowered us to make smarter, data-driven decisions, enabling us to provision our infrastructure with greater efficiency and confidence.

With these goals in mind, we embarked on a new journey of exploration and experimentation to uncover these insights.

Experiment setup 🧰

Collecting accurate data for this type of experiment was no easy feat. We needed to gather data from workloads that were as close to our production as possible, while also capturing how the system behaves under different phases of load. Since CPU usage patterns vary across workloads, we focused primarily on our flagship workloads. However, increasing the load could introduce small performance discrepancies, so our goal was to minimize disruption for our users.

Fortunately, a year ago, the Performance Engineering team developed an environment designed to meet these requirements, codenamed Large Unicorn Collider (LUC). This environment operates within a small portion of our Kubernetes clusters, mirroring the same architecture and configuration as our flagship workloads. It also has the flexibility to be hosted on dedicated machines, preventing interference from or with other workloads. Typically, the LUC environment remains idle, but when needed, we can direct a small, adjustable amount of traffic towards it. Activating or deactivating this traffic takes only seconds, allowing us to react quickly if performance concerns arise.

To accurately assess the impact of CPU utilization, we first established a baseline by sending moderate production traffic to a LUC Kubernetes pod hosted on one of its dedicated machines. This provided us with a benchmark for comparison. Importantly, the number of requests handled by the LUC pods remained constant throughout the experiment, ensuring consistent CPU load over time.

Once the baseline was set, we gradually increased CPU utilization using a tool called “stress,” which artificially occupies a specified number of CPU cores by running random processing tasks. Each instance type has a different number of CPU cores, so we adjusted the steps accordingly. However, the common factor across all instances was the total CPU utilization.

Note: It’s important to recognize that this is not a direct 1:1 comparison to the load generated by actual production workloads. The stress tool continuously runs mathematical operations, while our production workloads involve I/O operations and interrupts, which place different demands on system resources. Nevertheless, this approach still offers valuable insights into how our CPUs perform under load.

With the environment set up and our plan in place, we proceeded to collect as much data as possible to analyze the impact.

Results 📃

With our experiment setup finalized, let’s examine the data we gathered. As previously mentioned, we repeated the process across different instance types. Each instance type showed unique behavior and varying thresholds where performance started to decline.

As anticipated, CPU time increased for all instance types as CPU utilization rose. The graph below illustrates the CPU time per request as CPU utilization increases.

CPU time per request vs CPU utilization

The latency differences between instance types are expected due to the variations in CPU models. Focusing on the percentage increase in latency may provide more meaningful insights.

Latency percentage increase vs CPU utilization

In both graphs, one line stands out by deviating more than the others. We’ll examine this case in detail shortly.

Turbo Boost effect

An interesting observation is how CPU frequency changes as utilization increases, which can be attributed to Intel’s Turbo Boost Technology. Since all the instances we used are equipped with Intel CPUs, the impact of Turbo Boost is noticeable across all of them. In the graph below, you can see how the CPU frequency decreases as the CPU utilization increases. The red arrows are showing the CPU utilization level.

CPU Cores Frequency
CPU Cores Frequency

When CPU utilization remains at lower levels (around 30% or below), we benefit from increased core frequencies, leading to faster CPU times and, consequently, lower overall latency. However, as the demand for more CPU cores rises and utilization increases, we are likely to reach the CPU’s thermal and power limits, causing frequencies to decrease. In essence, lower CPU utilization results in better performance, while higher utilization leads to a decline in performance. For instance, a workload running on a specific node with approximately 30% CPU utilization will report faster response times compared to the same workload on the same VM when CPU utilization exceeds 50%.

Hyper-Threading

Variations in CPU frequency are not the only factors influencing performance changes. All our nodes have Hyper-Threading enabled, an Intel technology that allows a single physical CPU core to operate as two virtual cores. Although there is only one physical core, the Linux kernel recognizes it as two virtual CPU cores. The kernel attempts to distribute the CPU load across these cores, aiming to keep only one hardware thread (virtual core) busy per physical core. This approach is effective until we reach a certain level of CPU utilization. Beyond this threshold, we cannot fully utilize both virtual CPU cores, resulting in reduced performance compared to normal operation.

Finding the “Golden Ratio” of CPU utilization

Underutilized nodes lead to wasted resources, power, and space in our data centers, while nodes that are excessively utilized also create inefficiencies. As noted, higher CPU utilization results in decreased performance, which can give a misleading impression that additional resources are necessary, resulting in a cycle of over-provisioning. This issue is particularly pronounced with blocking workloads that do not follow an asynchronous model. As CPU performance deteriorates, each process can manage fewer tasks per second, making existing capacity inadequate. To achieve the optimal balance—the “Golden Ratio” of CPU utilization—we must identify a threshold where CPU utilization is sufficiently high to ensure efficiency without significantly impairing performance. Striving to keep our nodes near this threshold will enable us to utilize our current hardware more effectively alongside our existing software.

Since we already have experimental data demonstrating how CPU time increases with rising utilization, we can develop a mathematical model to identify this threshold. First, we need to determine what percentage of CPU time degradation is acceptable for our specific use case. This may depend on user expectations or performance Service Level Agreements (SLAs). Once we establish this threshold, it will help us select a level of CPU utilization that remains within acceptable limits.

We can plot the CPU utilization vs. CPU time (latency) and find the point where:

  • CPU utilization is high enough to avoid resource underutilization.
  • CPU time degradation does not exceed your acceptable limit.

A specific example derived from the data above can be illustrated in the following graph.

Percentage Increase in P50 Latency vs CPU Utilization

In this example, we aim to achieve less than 40% CPU time degradation, which would correspond to a CPU utilization of 61% on the specific instance.

Outlier case

As previously mentioned, there was a specific instance that displayed some outlying data points. Our experiment confirmed an already recognized issue where certain instances were not achieving their advertised maximum Turbo Boost CPU frequency. Instead, we observed steady CPU frequencies that fell below the maximum advertised value under low CPU utilization. In the example below, you can see an instance from a CPU family that advertises Turbo Boost frequencies above 3 GHz, but it is only reporting a maximum CPU frequency of 2.8 GHz.

CPU cores frequency
CPU cores frequency

This issue turned out to be caused by a disabled CPU C-state, which prevented the CPU cores from halting even when they were not in use. As a result, these cores were perceived as “busy” by the turbo driver, limiting our ability to take advantage of Turbo Boost benefits with higher CPU frequencies. By enabling the C-state and allowing for optimization and power reduction during idle mode, we observed the expected Turbo Boost behavior. This change had an immediate impact on the CPU time spent by our test workloads. The images below illustrate the prompt changes in CPU frequencies and latency reported following the C-state adjustment.

CPU cores frequency
CPU cores frequency
P50 CPU time on a request

Upon re-evaluating the percentage change in CPU time, we now observe similar behavior across all instances.

Percentage Increase in P50 Latency vs CPU Utilization

Wrap-up

As we anticipated many of these insights, our objective was to validate our theories using data from our complex system. While we confirmed that performance lowers as CPU utilization increases across different CPU families, by identifying optimal CPU utilization thresholds, we can achieve a better balance between performance and efficiency, ensuring that our infrastructure remains both cost-effective and high performing. Going forward, these insights will inform us of our resource provisioning strategies and help us maximize the effectiveness of our hardware investments.


Thank you for sticking with us until the end!! A special shout-out to @adrmike, @schlubbi, @terrorobe, the @github/compute-platform and finally the @github/performance-engineering team for their invaluable assistance throughout these experiments, data analysis, and for reviewing the content for accuracy and consistency. ❤️

The post Breaking down CPU speed: How utilization impacts performance appeared first on The GitHub Blog.

How we reduced initialisation time of Product Configuration Management SDK

Post Syndicated from Grab Tech original https://engineering.grab.com/how-we-reduced-grabx-sdk-initialisation-time

Introduction

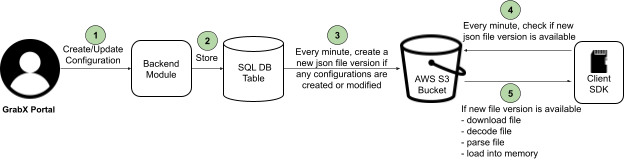
GrabX serves as Grab’s central platform for product configuration management. GrabX client services read product configurations through an SDK. This SDK reads the configurations in a way that’s eventually consistent, meaning it takes about a minute for any configuration updates to reach the client SDKs.

However, some GrabX SDK clients, particularly those that need to read larger configuration data (~400 MB), reported that the SDK takes an extended amount of time to initialise, approximately four minutes. This blog post details how we analysed and addressed this issue.

SDK Observations

GrabX clients have observed that the GrabX SDK requires several minutes to initialise. This results in what is known as ‘cold starts’, where the SDK takes an extended time to begin supporting the reading of configurations at startup. This challenge highlights the importance of efficient SDK start-up management, especially when a service handling a high volume of incoming traffic initiates new SDK instances to manage the load better. However, due to the extended SDK initialisation time, these instances continue to experience stress, potentially leading to service throttling.

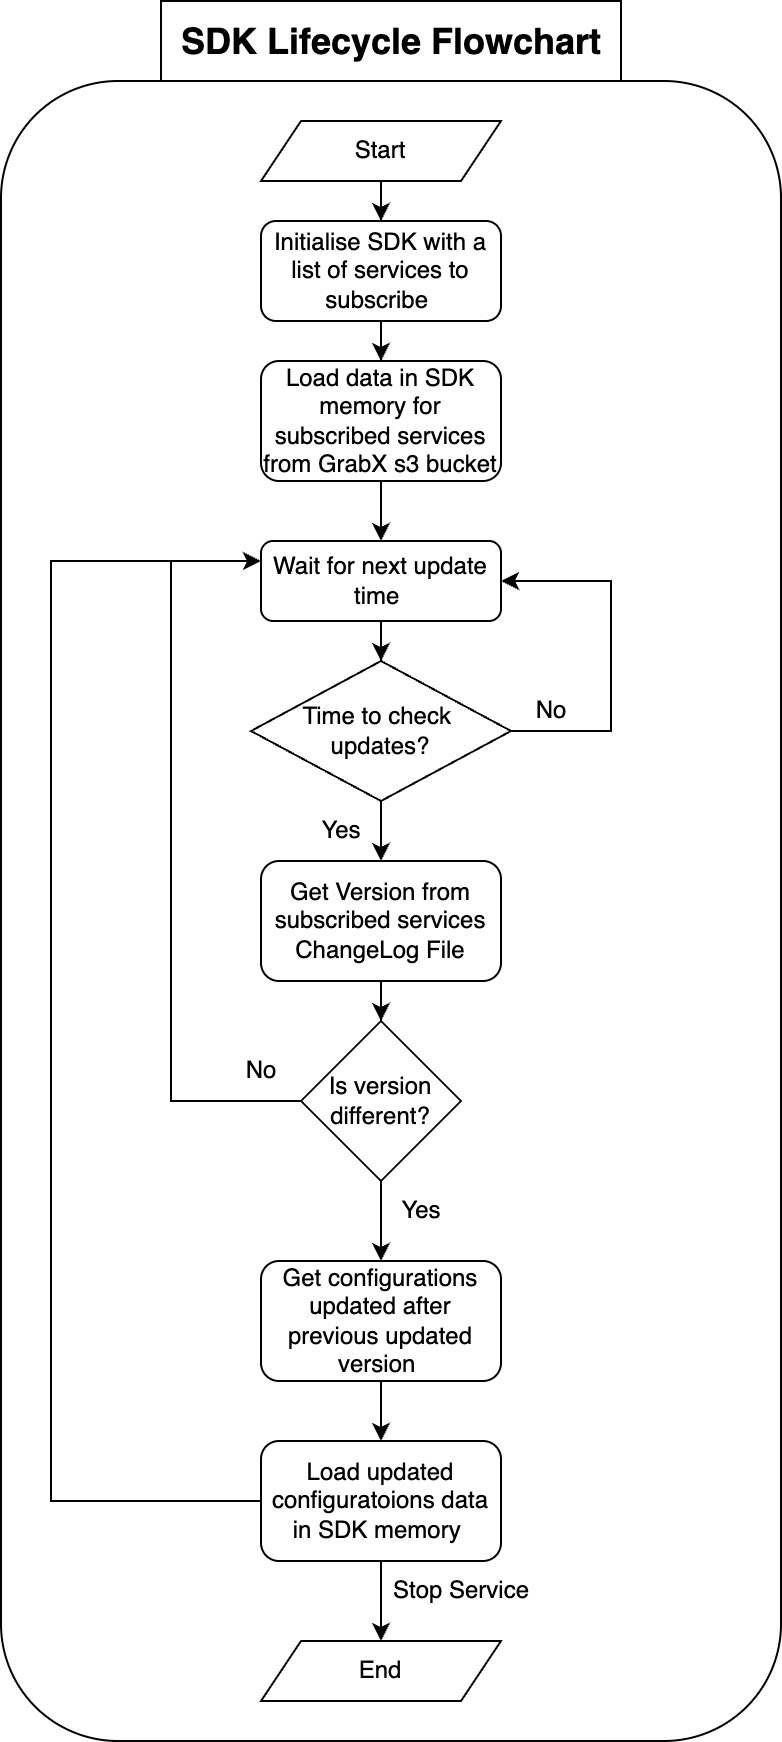
SDK Initialisation Workflow

The SDK initialisation flow described below is based on the improvements we proposed to the SDK design in our previous post. In that post, we suggested enhancing the SDK design by:

A. Implementing service-based data partitioning and storage in the AWS S3 bucket
B. Allowing service-based subscription of data for the SDK

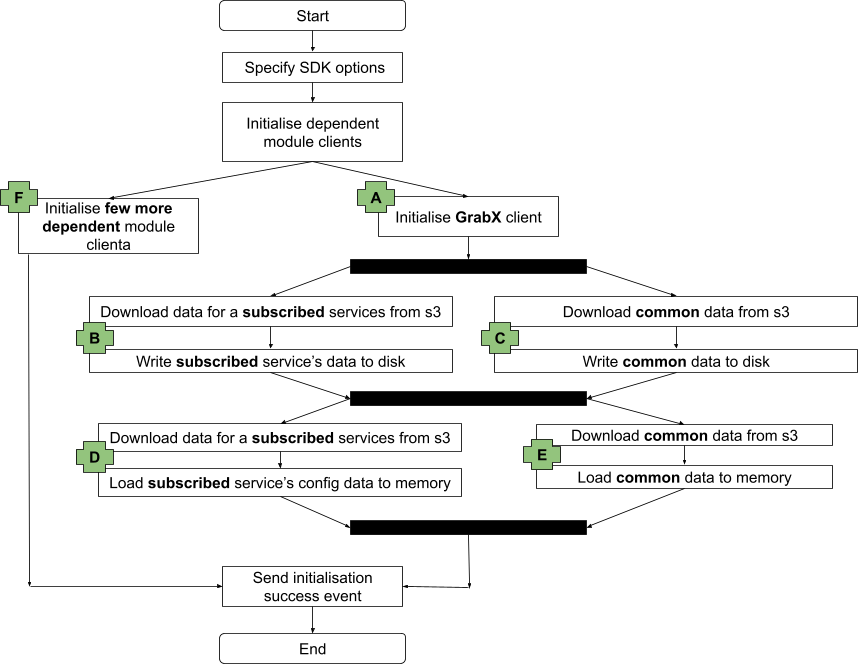
The following diagram provides a high-level overview of the initialisation process of the GrabX SDK, which can be divided into the following sequential steps:

  1. Set options that drive the behaviour of the SDK.
  2. Initialise dependent module clients.
  3. Initialise the GrabX client. (Highlighted as A in the diagram below)
  4. Download data for the SDK’s subscribed list of services from the AWS S3 bucket and store this data on the SDK instance disk. (Highlighted as B in the diagram below)
  5. Download common data needed by the SDK from the AWS S3 bucket and store this data on the SDK instance disk. This data is referred to as ‘common’ because it is required by all different client services. (Highlighted as C in the diagram below)
  6. Download data for the SDK’s subscribed list of services from the AWS S3 bucket and load this data into the SDK instance memory. (Highlighted as D in the diagram below)
  7. Download common data needed by the SDK from the AWS S3 bucket and load this data into the SDK instance memory. (Highlighted as E in the diagram below)
  8. Initialise dependent modules for resolving the configuration value. (Highlighted as F in the diagram below)

Proposed Solution

In order to address the issue of extended SDK initialisation time, we have decided to enhance the SDK initialisation design in multiple phases. Each phase focused on improving a specific part of the workflow.

Improvement Phase 1

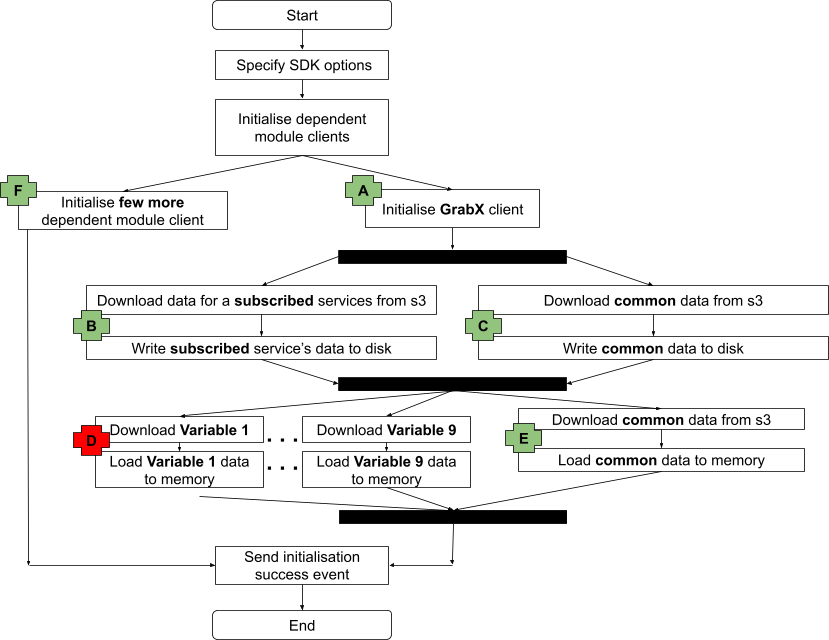
As discussed in the previous section, the GrabX SDK needs to load two separate sets of data: the subscribed services data and the common data. These two data sets are currently downloaded from the AWS S3 bucket and sequentially loaded into disk and memory.

In the first phase of our improvement plan, we decided to change the sequential data load to a concurrent data load for these two data sets, as illustrated in the following diagram. This alteration in the SDK initialisation workflow reduced the initialisation time by approximately 80%.


Improvement Phase 2

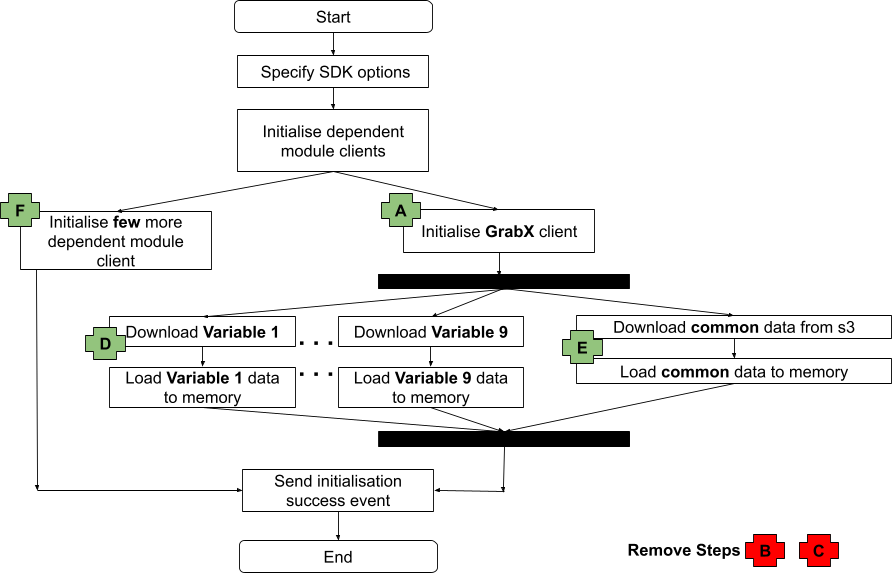
Building on the progress made in Phase 1, we next turned our attention to the issue of large configuration file sizes. As mentioned in the introduction, the extended SDK initialisation time was particularly noticeable for client services that needed to load larger amounts of data.

In this phase, we decided to implement an SDK design change that allows the SDK to concurrently download data from the AWS S3 bucket and load it into memory for all these large configurations within a subscribed service, as illustrated in the following diagram. This modification to the SDK initialisation workflow further reduced the initialisation time by approximately 6%.


Improvement Phase 3

Upon examining the SDK’s behaviour, we observed that the SDK is both persisting configuration data downloaded from the AWS S3 bucket to disk and loading the data into memory. We understand that the data is loaded into memory to reduce the latency of configuration reads. The data is stored on disk to support a fallback mechanism, which is activated in a very specific use case: when the client SDK instance restarts and there is a connectivity issue with AWS S3 for downloading configuration files. In this scenario, the SDK will read the configuration data stored on disk. However, this data could be outdated as it is not freshly downloaded from the AWS S3 bucket, and most client services require the most recent data.

Therefore, we realised that the fallback mechanism, for which data is persisted on disk, actually conflicts with the desired SDK behaviour for most client services. As a result, we decided to eliminate the SDK initialisation step that downloads configuration data from AWS S3 and persists it on disk. If the SDK initialisation fails to connect to the AWS S3 bucket and download data, client services can then take the necessary action, such as retrying initialisation. This modification further reduced the initialisation time by approximately 50% compared to the improvement achieved in Phase 2.


Conclusion

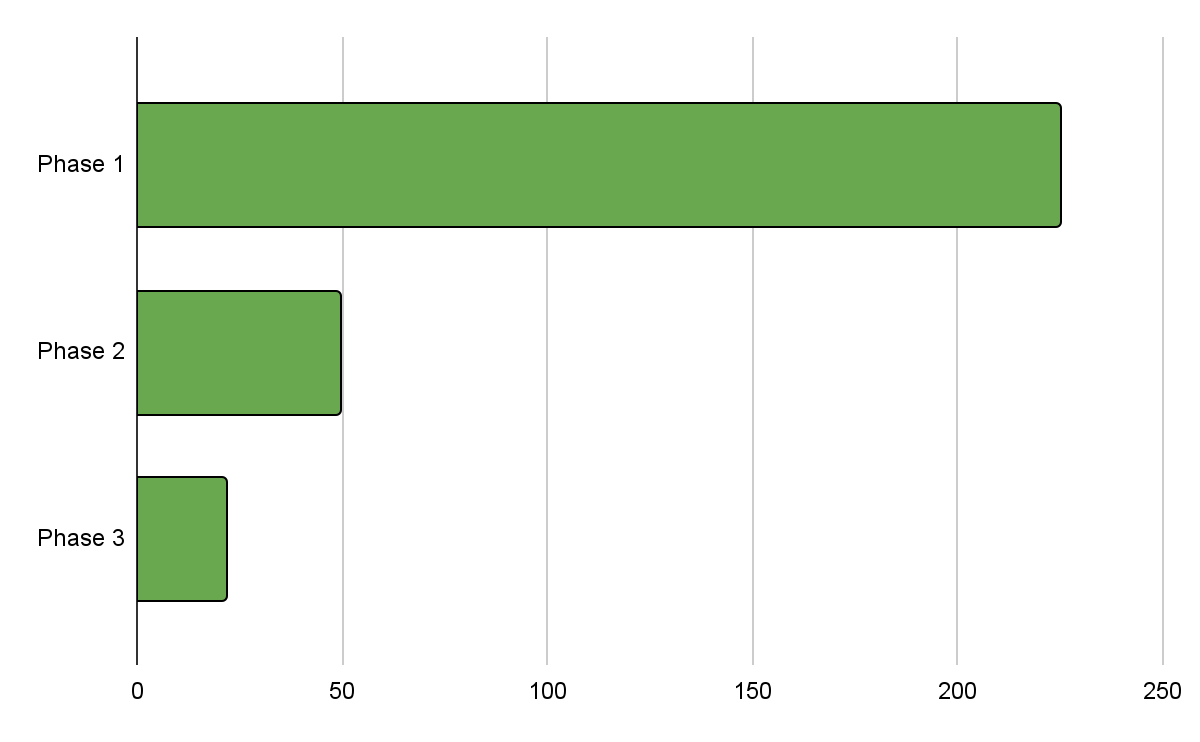
We benchmarked the proposed solution with a variety of services, each having different configuration data sizes. Our findings suggest that the proposed solution has the potential to reduce initialisation time by up to 90%.

The following chart illustrates the phase-wise reduction in initialisation time achieved through the improvements made to the GrabX SDK.


Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
How to make Storybook Interactions respect user motion preferences

Post Syndicated from Kendall Gassner original https://github.blog/engineering/user-experience/how-to-make-storybook-interactions-respect-user-motion-preferences/


Recently, while browsing my company’s Storybook, I came across something that seemed broken: a flickering component that appeared to be re-rendering repeatedly. The open source tool that helps designers, developers, and others build and use reusable components was behaving weirdly. As I dug in, I realized I was seeing the unintended effects of the Storybook Interactions addon, which allows developers to simulate user interactions within a story, in action.

Storybook Interactions can be a powerful tool, enabling developers to simulate and test user behaviors quickly. But if you’re unfamiliar with Interactions—especially if you’re just looking to explore available components—the simulated tests jumping around on the screen can feel disorienting.

This can be especially jarring for users who have the prefers-reduced-motion setting enabled in their operating system. When these users encounter a story that includes an interaction, their preferences are ignored and they have no option to disable or enable it. Instead, the Storybook Interaction immediately plays on page load, regardless. These rapid screen movements can cause disorientation for users or in some cases can even trigger a seizure.

At this time, Storybook does not have built-in capabilities to toggle interactions on or off. Until this feature can be baked in I am hoping this blog will provide you with an alternative way to make your work environment more inclusive. Now, let’s get into building an addon that respects user’s motion preferences and allows users to toggle interactions on and off.

Goals

  1. Users with prefers-reduced-motion enabled MUST have interactions off by default.
  2. Users with prefers-reduced-motion enabled MUST have a way to toggle the feature on or off without altering their operating system user preferences.
  3. All users SHOULD have a way to toggle the feature on or off without altering their user preferences.

Let’s get started

Step 1: Build a Storybook addon

Storybook allows developers to create custom addons. In this case, we will create one that will allow users to toggle Interactions on or off, while respecting the prefers-reduced-motion setting.

Add the following code to a file in your project’s .storybook folder:

import React, {useCallback, useEffect} from 'react'

import {IconButton} from '@storybook/components'
import {PlayIcon, StopIcon} from '@storybook/icons'

export const ADDON_ID = 'toggle-interaction'
export const TOOL_ID = `${ADDON_ID}/tool`

export const INTERACTION_STORAGE_KEY = 'disableInteractions'

export const InteractionToggle = () => {
  const [disableInteractions, setDisableInteractions] = React.useState(
       window?.localStorage.getItem(INTERACTION_STORAGE_KEY) === 'true',
  )

  useEffect(() => {
    const reducedMotion = matchMedia('(prefers-reduced-motion)')

    if (window?.localStorage.getItem(INTERACTION_STORAGE_KEY) === null && reducedMotion.matches) {
      window?.localStorage?.setItem(INTERACTION_STORAGE_KEY, 'true')
      setDisableInteractions(true)
    }
  }, [])

  const toggleMyTool = useCallback(() => {
    window?.localStorage?.setItem(INTERACTION_STORAGE_KEY, `${!disableInteractions}`)
    setDisableInteractions(!disableInteractions)
      // Refreshes the page to cause the interaction to stop/start
      window.location.reload()
}, [disableInteractions, setDisableInteractions])

  return (
    <IconButton
      key={TOOL_ID}
      aria-label="Disable Interactions"
      onClick={toggleMyTool}
      defaultChecked={disableInteractions}
      aria-pressed={disableInteractions}
    >
      {disableInteractions ? <PlayIcon /> : <StopIcon />}
      Interactions
    </IconButton>
  )
}

Code breakdown

This addon stores user preferences for Interactions using window.localStorage. When the addon first loads, it checks whether the preference is already set and, if so, it defaults to the user’s preference.

const [disableInteractions, setDisableInteractions] = React.useState(
       window?.localStorage.getItem(INTERACTION_STORAGE_KEY) === 'true',
  )

This useEffect hook checks if a user has their motion preferences set to prefers-reduced-motion and ensures that Interactions are turned off if the user hasn’t already set a preference in Storybook.

useEffect(() => {
    const reducedMotion = matchMedia('(prefers-reduced-motion)')

    if (window?.localStorage.getItem(INTERACTION_STORAGE_KEY) === null && reducedMotion.matches) {
      window?.localStorage?.setItem(INTERACTION_STORAGE_KEY, 'true')
      setDisableInteractions(true)
    }
  }, [])

When a user clicks the toggle button, preferences are updated and the page is refreshed to reflect the changes.

const toggleMyTool = useCallback(() => {
    window?.localStorage?.setItem(INTERACTION_STORAGE_KEY, `${!disableInteractions}`)
    setDisableInteractions(!disableInteractions)
      // Refreshes the page to cause the interaction to stop/start
      window.location.reload()
  }, [disableInteractions, setDisableInteractions])

Step 2: Register your new addon with Storybook

In your .storybook/manager file, register your new addon:

addons.register(ADDON_ID, () => {
  addons.add(TOOL_ID, {
    title: 'toggle interaction',
    type: types.TOOL as any,
    match: ({ viewMode, tabId }) => viewMode === 'story' && !tabId,
    render: () => <InteractionToggle />,
  })
})

This adds the toggle button to the Storybook toolbar, which will allow users to change their Storybook Interaction preferences.

Step 3: Add functionality to check user preferences

Finally, create a function that checks whether Interactions should be played and add it to your interaction stories:

import {INTERACTION_STORAGE_KEY} from './.storybook/src/InteractionToggle'

export const shouldInteractionPlay = () => {
  const disableInteractions = window?.localStorage?.getItem(INTERACTION_STORAGE_KEY)
  return disableInteractions === 'false' || disableInteractions === null
}


 export const SomeComponentStory = {
  render: SomeComponent,
  play: async ({context}) => {
    if (shouldInteractionPlay()) {
...
    }
  })
 }

Wrap-up

With this custom addon, you can ensure your workplace remains accessible to users with motion sensitivities while benefiting from Storybook’s Interactions. For those with prefers-reduced-motion enabled, motion will be turned off by default and all users will be able to toggle interactions on or off.

The post How to make Storybook Interactions respect user motion preferences appeared first on The GitHub Blog.

Metasense V2: Enhancing, improving and productionisation of LLM powered data governance

Post Syndicated from Grab Tech original https://engineering.grab.com/metasense-v2

Introduction

In the initial article, LLM Powered Data Classification, we addressed how we integrated Large Language Models (LLM) to automate governance-related metadata generation. The LLM integration enabled us to resolve challenges in Gemini, such as restrictions on the customisation of machine learning classifiers and limitations of resources to train a customised model. Gemini is a metadata generation service built internally to automate the tag generation process using a third-party data classification service. We also focused on LLM-powered column-level tag classifications. The classified tags, combined with Grab’s data privacy rules, allowed us to determine sensitivity tiers of data entities. The affordability of the model also enables us to scale it to cover more data entities in the company. The initial model scanned more than 20,000 data entries, at an average of 300-400 entities per day. Despite its remarkable performance, we were aware that there was room for improvement in the areas of data classification and prompt evaluation.

Improving the model post-rollout

Since its launch in early 2024, our model has gradually grown to cover the entire data lake. To date, the vast majority of our data lake tables have undergone analysis and classification by our model. This has significantly reduced the workload for Grabbers. Instead of manually classifying all new or existing tables, Grabbers can now rely on our model to assign the appropriate classification tier accurately.

Despite table classification being automated, the data pipeline still requires owners to manually perform verification to prevent any misclassifications. While it is impossible to entirely eliminate human oversight from critical machine learning workflows, the team has dedicated substantial time post-launch to refining the model, thereby safely minimising the need for human intervention.

Utilising post-rollout data

Following the deployment of our model and receipt of extensive feedback from table owners, we have accumulated a large dataset to further enhance the model. This data, coupled with the dataset of manual classifications from the Data Governance Office to ensure compliance with information classification protocols, serves as the training and testing datasets for the second iteration of our model.

Model improvements with prompt engineering

Expanding the evaluation and testing data allowed us to uncover weaknesses in the previous model. For instance, we discovered that seemingly innocuous table columns like “business email” could contain entries with Personal Identifiable Information (PII) data.

An example of this would be a business that uses a personal email address containing a legal name—a discrepancy that would be challenging for even human reviewers to detect. Additionally, we discovered nested JSON structures occasionally included personal names, phone numbers, and email addresses hidden among other non-PII metadata. Lastly, we identified passenger communications with Grab occasionally mentioning legal names, phone numbers, and other PII, despite most of the content being non-PII.

Ultimately, we hypothesised the model’s main issue was model capacity. The model displayed difficulty focusing on large data samples containing a mixture of PII and non-PII data despite having a good understanding of what constitutes PII. Just like humans, when given high volumes of tasks to work on simultaneously, the model’s effectiveness is reduced. In the original model, 13 out of 21 tags were aimed at distinguishing different types of non-PII data. This took up significant model capacity and distracted the model from its actual task: identifying PII data.

To prevent the model from being overwhelmed, large tasks are divided into smaller, more manageable tasks, allowing the model to dedicate more attention to each task. The following measures were taken to free up model capacity:

  1. Splitting the model into two parts to make problem solving more manageable.
    • One part for adding PII tags.
    • Another part for adding all other types of tags.
  2. Reducing the number of tags for the first part from 21 to 8 by removing all non-PII tags. This simplifies the task of differentiating types of data.

  3. Using clear and concise language, removing unnecessary detail. This was done by reducing word count in prompt from 1,254 to 737 words for better data analysis.

  4. Splitting tables with more than 150 columns into smaller tables. Fewer table rows means that the LLM has sufficient capacity to focus on each column.

Enabling rapid prompt experimentation and deployment

In our quest to facilitate swift experimentation with various prompt versions, we have empowered a diverse team of data scientists and engineers to work together effectively on the prompts and service. This has been made possible by upgrading our model architecture to incorporate the LangChain and LangSmith frameworks.

LangChain introduces a novel framework that streamlines the process from raw input to the desired outcome by chaining interoperable components. LangSmith, on the other hand, is a unified DevOps platform that fosters collaboration among various team members and developers, including product managers, data scientists, and software engineers. It simplifies the processes of development, collaboration, testing, deployment, and monitoring for all involved.

Our new backend leverages LangChain to construct an updated model that supports classification tasks for both non-PII and PII tagging. Integration with LangSmith enables data scientists to directly develop prompt templates and conduct experiments via the LangSmith user interface. In addition, managing the evaluation dataset on LangSmith provides a clear view of the performance of prompts across multiple custom metrics.

The integration of LangChain and LangSmith has significantly improved our model architecture, fostering collaboration and continuous improvement. This has not only streamlined our processes but also enhanced the transparency of our performance metrics. By harnessing the power of these innovative tools, we are better equipped to deliver high-quality, efficient solutions.

The benefits of the LangChain and LangSmith framework enhancements in Metasense are summarised as follows:

Streamlined prompt optimisation process.

Data scientists can create, update, and evaluate prompts directly on the LangSmith user interface and save them in commit mode. For rapid deployment, the prompt identifier in service configurations can be easily adjusted.

Figure 1: Streamlined prompt optimisation process.

Transparent prompt performance metrics.

LangSmith’s capabilities allow us to effortlessly run evaluations on a dataset and obtain performance metrics across multiple dimensions, such as accuracy, latency, and error rate.

Assuring quality in perpetuity

With exceptionally low misclassification rates recorded, table owners can place greater trust in the model’s outputs and spend less time reviewing them. Nevertheless, as a prudent safety measure, we have set up alerts to monitor misclassification rates periodically, sounding an internal alarm if the rate crosses a defined threshold. A model improvement protocol has also been set in place for such alarms.

Conclusion

The integration of LLM into our metadata generation process has significantly improved our data classification capabilities, reducing manual workloads and increasing accuracy. Continuous improvements, including the adoption of LangChain and LangSmith frameworks, have streamlined prompt optimisation and enhanced collaboration among our team. With low misclassification rates and robust safety measures, our system is both reliable and scalable, fostering trust and efficiency. In conclusion, these advancements ensure we remain at the forefront of data governance, delivering high-quality solutions and valuable insights to our stakeholders.

We would like to express our sincere gratitude to Infocomm Media Development Authority (IMDA) for supporting this initative.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
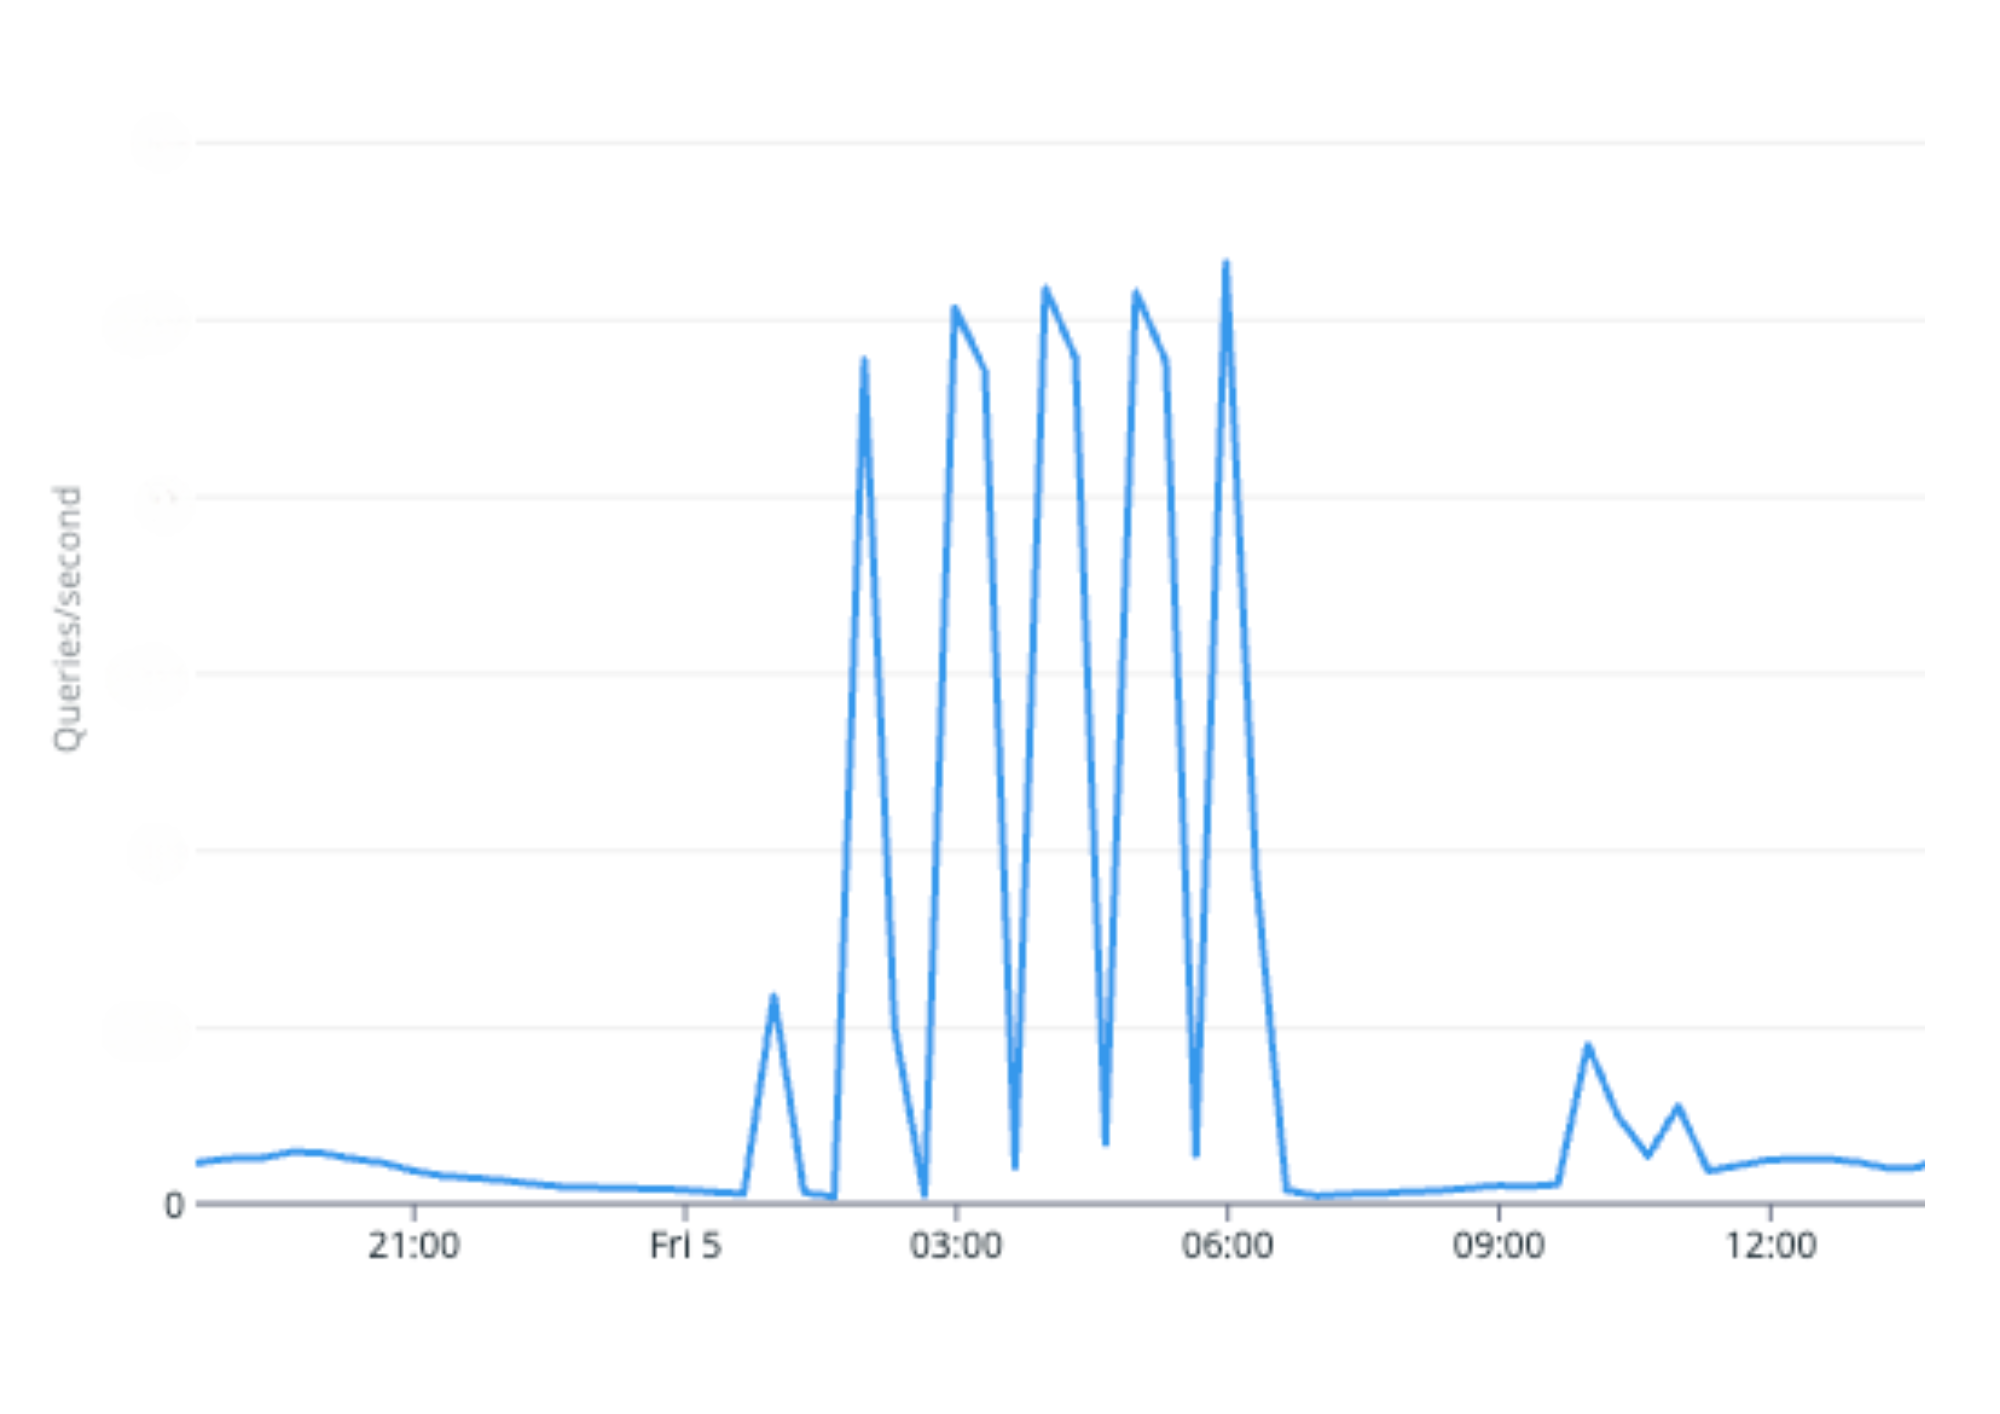
How we reduced peak memory and CPU usage of the product configuration management SDK

Post Syndicated from Grab Tech original https://engineering.grab.com/reduced-memory-cpu-usage-grabx-sdk

Introduction

GrabX is Grab’s central platform for product configuration management. It has the capacity to control any component within Grab’s backend systems through configurations that are hosted directly on GrabX.

GrabX clients read these configurations through an SDK, which reads the configurations in a way that’s asynchronous and eventually consistent. As a result, it takes about a minute for any updates to the configurations to reach the client SDKs.

In this article, we discuss our analysis and the steps we took to reduce the peak memory and CPU usage of the SDK.

Observations on potential SDK improvements

Our GrabX clients noticed that the GrabX SDK tended to require high memory and CPU usage. From this, we saw opportunities for further improvements that could:

  • Optimise the tail latencies of client services.
  • Enable our clients to use their resources more effectively.
  • Reduce operation costs and improve the efficiency of using the GrabX SDK.
  • Accelerate the adoption of GrabX by Grab’s internal services.

SDK design

At a high-level, creating, updating, and serving configuration values via the GrabX SDK involved the following process:

Figure 1. Previous GrabX SDK design.
  1. The process begins when GrabX clients either create or update configurations. This is done through the GrabX web portal or by making an API call.
  2. Once the configurations are created or updated, the GrabX backend module takes over. It stores the new configuration into an SQL database table.
  3. The GrabX backend ensures that the latest configuration data is available to client SDKs.

    a. The GrabX backend checks every minute for any newly created or updated configurations.

    b. If there are new or updated configurations, GrabX backend creates a new JSON file. This file contains all existing and newly created configurations. It’s important to note that all configurations across all services are stored in a single JSON file.

    c. The backend module uploads this newly created JSON file to an AWS S3 bucket.

    d. The backend module assigns a version number to the new JSON file and updates a text file in the AWS S3 bucket. This text file stores the latest JSON file version number. The client SDK refers to this version file to check if a newer version of the configuration data is available.

  4. The client SDK performs a check on the version file every minute to determine if a newer version is available. This mechanism is crucial to maintain data consistency across all instances of a service. If any instance fell out of sync, it would be brought back in sync within a minute.
  5. If a new version of the configuration JSON file is available, the client SDK downloads this new file. Following the download, it loads the configuration data into memory. Storing the configuration data in memory reduces the read latency for the configurations.

Areas of improvement for existing SDK design

In this section we outline the areas of improvement we identified within the SDK design.

Service-based data partitioning

We saw an opportunity for service-based data partitioning. The configuration data for all services was consolidated into a single JSON file. Upon studying the data read patterns of client services, we observed that most services primarily needed to access configuration data specific to their own service. However, the present design required storing configuration data for all other services. This resulted in unnecessary memory consumption.

Retaining only new version of configuration in the same file

By using a single JSON file for storing old and new configuration data, we saw a significant increase in the size of the JSON file.

The SDK only needs the full data when it starts; the more common case is that it needs to stay updated with the latest configuration. Even in that scenario, the SDK needed to fetch a complete new JSON file every minute no matter the size of the updates. Consequently, the process of downloading, decoding, and loading high volumes of data at a high frequency (every minute) caused the client SDK to spike in memory and CPU usage.

More efficient JSON decoding

An additional factor which contributed to memory and CPU usage during the decoding phase was the inefficiency of the default JSON decode library to decode this large (>100MB) JSON file. Decoding this JSON file was heavy on available CPU resources, which tended to starve the service of its ability to handle incoming requests. This manifested as increasing the P99 latency of the service.

Figure 2. Graph illustrating the increased P99 latency due to CPU throttling for a service.

Implemented solution

We proposed modifications to the existing SDK design, which we discuss in this section.

Partition data by service

The proposed solution involved partitioning the data based on services. We chose this approach because a single configuration typically belonged to a single service, and most services primarily needed to read configurations that pertained to their own service.

Upon analysing the distribution of service-configuration, we discovered that 98% of client services required less than 1% of the total configuration data. Despite this, they were required to maintain and reload 100% of the configuration data. Furthermore, the service with the largest number of configurations only required 20% of the total configuration data.

Therefore, we proposed a shift towards service-based partitioning of configuration data. This allowed individual client services to access only the data they needed to read.

Figure 3. Graph showing the number of services with varying amounts of configurations.

Create separate JSON files for each configuration

Our proposal also included creating a separate JSON file for each configuration in a service. Previously, all data was stored in a single JSON file housed in an AWS S3 bucket, which supported a maximum of 3,500 write/update requests and 5,500 read requests per second.

By storing each configuration in a separate JSON file, we were able to create a different S3 prefix for each configuration file. These S3 prefixes helped us to maximise S3 throughput by enhancing the read/write performance for each configuration. AWS S3 can handle at least 3,500 PUT/COPY/POST/DELETE requests or 5,500 GET/HEAD requests per second for each partitioned Amazon S3 prefix.

Therefore, with each configuration’s data stored in a separate S3 file with a different prefix, the GrabX platform could achieve a throughput of 5,500 read requests and 3,500 write/update requests per second per configuration. This was beneficial for boosting read/write capacity when needed.

Implement a service-level changelog

We proposed to create a changelog file at the service level. In other words, a changelog file was created for each service. This file was used to keep track of the latest update version, as well as previous service configuration update versions. This file also recorded the configurations which were created or updated in each version. This enables the SDK to accurately identify the configurations that were created or updated in each update version. This was useful to update the specific configurations belonging to a service on the client side.

Implement service-based SDK

We proposed that SDK client services should be allowed to subscribe to a list of services for which they need to read configuration data. The SDK was initialised with data of the subscribed services and received updates only for configurations corresponding to the subscribed services.

Figure 4. This flowchart shows our proposed service-based SDK implementation.

The SDK only sought updates for the subscribed services. The client SDK needed to read the changelog file for each of the subscribed services, comparing the latest changelog version against the SDK version number. Whenever a newer changelog version was available, the SDK updated the variables with the latest version.

This approach significantly reduced the volume of data that the SDK needed to download, decode, and load into memory during both initialisation and each subsequent update.

Conclusion

In summary, we identified ways to optimise CPU and memory usage in the GrabX SDK. Our analysis revealed that frequent high resource consumption hindered the wider adoption of GrabX. We proposed a series of modifications, including partitioning data by service and creating separate JSON files for each configuration.

After benchmarking the proposed solution with a variety of configuration data sizes, we found that the solution has the potential to reduce memory utilisation by up to 70% and decrease the maximum CPU utilisation by more than 50%. These improvements significantly enhance the performance and scalability of the GrabX SDK.

Figure 5. Bar charts showcasing memory(MB) & CPU(%) utilisation for Service A before and after using the discussed solution.

Moving forward, we plan to continue optimising the GrabX SDK by exploring additional improvements, such as reducing its initialisation time. These efforts aim to make GrabX an even more robust and reliable solution for product configuration management within Grab’s ecosystem.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
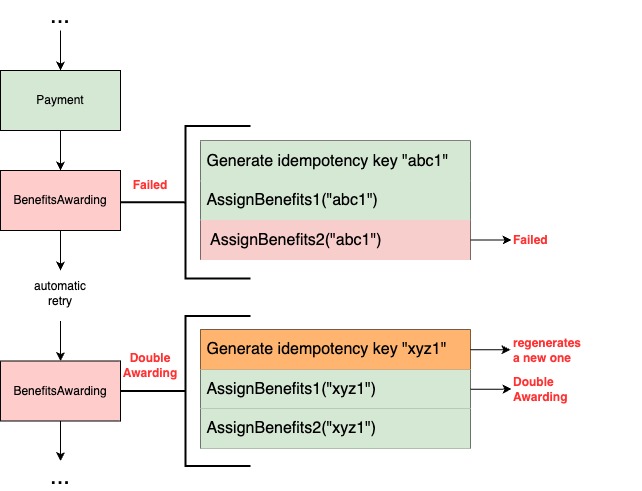
LLM-assisted vector similarity search

Post Syndicated from Grab Tech original https://engineering.grab.com/llm-assisted-vector-similarity-search

Introduction

As the complexity of data retrieval requirements continue to grow, traditional search methods often struggle to provide relevant and accurate results, especially for nuanced or conceptual queries. Vector similarity search has emerged as a powerful technique for finding semantically similar information. It refers to finding vectors in a large dataset that are most similar to a given query vector, typically using some distance or similarity measure. The concept originated in the 1960s with the work by Minsky and Papert on nearest neighbour search 1. Since then, the idea has evolved substantially with modern approaches often using approximate methods to enable fast search in high-dimensional spaces, such as locality-sensitive hashing 2 and graph-based indexing 3.

Recently, vector similarity search has become a crucial component in many machine learning and information retrieval applications. It is one of the key technologies that popularised the idea of Retrieval Augmented Generation (RAG) 4 which increased the applicability of Transformer 5 based Generative Large Language Models (LLMs) 6 in domain-specific tasks without requiring any further training or fine-tuning. However, the effectiveness of the vector search can be limited when dealing with intricate queries or contextual nuances. For example, from a typical vector similarity search perspective, “I like fishing” and “I do not like fishing” may be quite close to each other, while in reality, they are the exact opposite. In this blog post, we discuss an approach that we experimented with that combines vector similarity search with LLMs to enhance the relevance and accuracy of search results for such complex and nuanced queries. We leverage the strengths of both techniques: vector similarity search for efficient shortlisting of potential matches, and LLMs for their ability to understand natural language queries and rank the shortlisted results based on their contextual relevance.

Proposed solution

The proposed solution involves a two-step process:

  1. Vector similarity search: We first perform a vector similarity search on the dataset to obtain a shortlist of potential matches (e.g., top 10-50 results) for the given query. This step leverages the efficiency of vector similarity search to quickly narrow down the search space.

  2. LLM-assisted ranking: The shortlisted results from the vector similarity search are then fed into an LLM, which ranks the results based on their relevance to the original query. The LLM’s ability to understand natural language queries and contextual information helps in identifying the most relevant results from the shortlist.

By combining these two steps, we aim to achieve the best of both worlds: the efficiency of vector similarity search for initial shortlisting, and the contextual understanding and ranking capabilities of LLMs for refining the final results.

Figure 1. Similarity search and the proposed LLM-assisted similarity search.

Experiment

Datasets

To evaluate the effectiveness of our proposed solution, we conducted experiments on two small synthetic datasets in CSV format that we curated using GPT-4o 7.

  • Food dataset: A collection of 100 dishes with their titles and descriptions.
  • Tourist spots dataset: A collection of 100 tourist spots in Asia, including their names, cities, countries, and descriptions.

It is important to note that we primarily focus on performing similarity search on structured data such as description of various entities in a relational database.

Setup

Our experimental setup included a Python script for vector similarity search leveraging Facebook AI Similarity Search (FAISS) 8, a library developed by Facebook that offers efficient similarity search, and OpenAI’s embeddings (i.e., text-embedding-ada-002) 9 to generate the vector embeddings needed for facilitating the vector search. For our proposed solution, an LLM component (i.e., GPT-4o) was included in the setup in addition to the FAISS-based similarity search component.

Observations

To compare the performance of the proposed approach of LLM-assisted vector similarity search as outlined in the “Proposed solution” section with the raw vector similarity search, we conducted both techniques on our two synthetic datasets. With the raw vector search, we get the top three matches for a given query. For our proposed technique, we first get a shortlist of 15 entity matches from FAISS for the same query, and supply the shortlist and the original query to LLM with some descriptive instructions in the prompt to find the top three matches from the provided shortlist.

From the experiments, in simpler cases where the queries were straightforward and directly aligned with the textual content of the data, both the raw similarity search and the LLM-assisted similarity search demonstrated comparable performance. However, as the queries became more complex, involving additional constraints, negations, or conceptual requirements, the LLM-assisted search exhibited a clear advantage over the raw similarity search. The LLM’s ability to understand context and capture subtleties in the queries allowed it to filter out irrelevant results and rank the most appropriate ones higher, leading to improved accuracy.

Here are a few examples where the LLM-assisted similarity search performed better:

Food dataset

Query: “food with no fish or shrimp”

Raw similarity search result:

- title: Tempura, description: A Japanese dish of seafood or vegetables that have been battered and deep fried.
- title: Ceviche, description: A seafood dish popular in Latin America, made from fresh raw fish cured in citrus juices.
- title: Sushi, description: A Japanese dish consisting of vinegared rice accompanied by various ingredients such as seafood and vegetables.

LLM-assisted similarity search result:

- title: Chicken Piccata, description: Chicken breasts cooked in a sauce of lemon, butter, and capers.
- title: Chicken Alfredo, description: An Italian-American dish of pasta in a creamy sauce made from butter and Parmesan cheese.
- title: Chicken Satay, description: Grilled chicken skewers served with peanut sauce.

Observation: The LLM correctly filtered out dishes containing fish or shrimp, while the raw similarity search failed to do so, presumably due to the presence of negation in the query.

Tourist spots dataset

Query: “exposure to wildlife”

Raw similarity search result:

- name: Ocean Park, city: Hong Kong, country: Hong Kong, description: Marine mammal park and oceanarium.
- name: Merlion Park, city: Singapore, country: Singapore, description: Iconic statue with the head of a lion and body of a fish.
- name: Manila Bay, city: Manila, country: Philippines, description: A natural harbor known for its sunset views.

LLM-assisted similarity search result:

- name: Ocean Park, city: Hong Kong, country: Hong Kong, description: Marine mammal park and oceanarium.
- name: Chengdu Research Base, city: Chengdu, country: China, description: A research center for giant panda breeding.
- name: Mount Hua, city: Shaanxi, country: China, description: Mountain known for its dangerous hiking trails.

Observation: Two out of the top three matches by the LLM-assisted technique seem relevant to the query while only one result from the raw similarity search is relevant and the other two being somewhat irrelevant to the query. The LLM identified the relevance of a research base for giant panda breeding to the “exposure to wildlife”, which the raw similarity search ignored in its ranking.

These examples provide a glimpse into the utility of LLMs in finding more relevant matches in scenarios where the queries involved additional context, constraints, or conceptual requirements beyond simple keyword matching. On the other hand, when the queries were more straightforward and focused on specific keywords or phrases present in the data, both approaches demonstrated comparable performance. For instance, queries like “Japanese food” or “beautiful mountains” yielded similar results from both the raw similarity search and the proposed LLM-assisted approach.

Overall, the LLM-assisted vector search exhibited a clear advantage in handling complex queries, leveraging its ability to understand natural language and contextual information. However, for simpler queries, the raw similarity search remained a viable option, especially when computational efficiency is a concern.

Conclusion

The experiments demonstrated the potential of combining vector similarity search with LLMs to enhance the relevance and accuracy of search results, particularly for complex and nuanced queries. While vector similarity search alone can provide reasonable results for straightforward queries, the LLM-assisted approach shines when dealing with queries that require a deeper understanding of context, nuances, and conceptual relationships. By leveraging the natural language understanding capabilities of LLMs, this approach can better capture the intent behind complex queries and provide more relevant search results.

Our experiment was limited to using a small volume of structured data (100 data points in each dataset) with a limited number of queries. However, we have witnessed similar enhancement in search result relevance when we deployed this solution internally within Grab for larger datasets, for example, 4500+ rows of data stored in a relational database.

Nevertheless, it is important to note that the effectiveness of this approach may still depend on the quality and complexity of the data, as well as the specific use case and query patterns. We believe it is still worthwhile to evaluate the proposed approach for more diverse (e.g., beyond CSV) and larger datasets. An interesting future work can be varying the size of the shortlist from the similarity search and observing how it impacts the overall search relevance when using the proposed approach. In addition, for real world applications, the performance implications in terms of additional latency introduced by the additional LLM query must also be considered.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
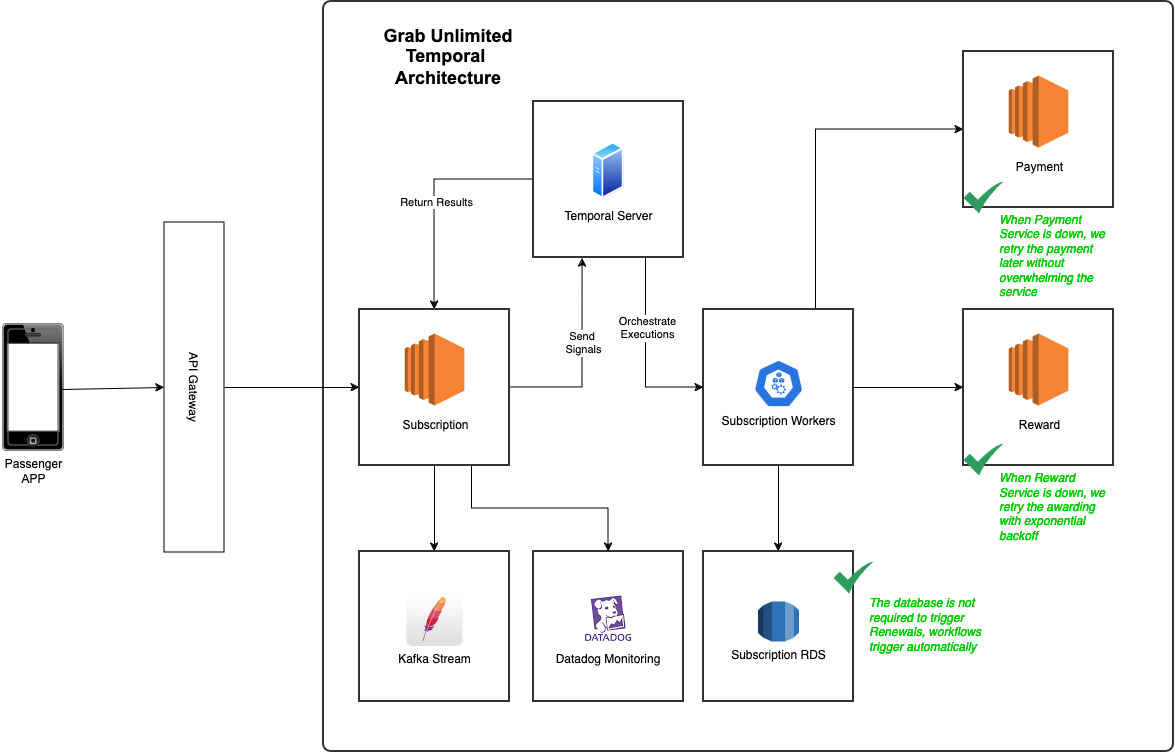
References

  1. M. Minsky and S. Papert, Perceptrons: An Introduction to Computational Geometry. MIT Press, 1969. ↩

  2. P. Indyk and R. Motwani, “Approximate nearest neighbors: Towards removing the curse of dimensionality,” in Proceedings of the Thirtieth Annual ACM Symposium on Theory of Computing, 1998. ↩

  3. Y. Malkov and D. Yashunin, “Efficient and robust approximate nearest neighbor search using hierarchical navigable small world graphs,” IEEE Transactions on Pattern Analysis and Machine Intelligence, 2020. ↩

  4. P. Lewis, E. Perez, A. Piktus, F. Petroni, V. Karpukhin, N. Goyal, and D. Kiela, “Retrieval-augmented generation for knowledge-intensive NLP tasks,” in Advances in Neural Information Processing Systems, 2020. ↩

  5. A. Vaswani, “Attention is all you need,” in Advances in Neural Information Processing Systems, 2017. ↩

  6. A. Radford, “Improving language understanding by generative pre-training,” 2018. ↩

  7. “Hello GPT-4o,” OpenAI, May 2024. [Online]. Available: https://openai.com/index/hello-gpt-4o/. [Accessed: Oct. 6, 2024]. ↩

  8. M. Douze, A. Guzhva, C. Deng, J. Johnson, G. Szilvasy, P. E. Mazaré, and H. Jégou, “The faiss library,” arXiv preprint arXiv:2401.08281, 2024. ↩

  9. “Embeddings,” OpenAI API. [Online]. Available: https://platform.openai.com/docs/guides/embeddings. [Accessed: Oct. 6, 2024]. ↩

Building Vectorize, a distributed vector database, on Cloudflare’s Developer Platform

Post Syndicated from Jérôme Schneider original https://blog.cloudflare.com/building-vectorize-a-distributed-vector-database-on-cloudflare-developer-platform

Vectorize is a globally distributed vector database that enables you to build full-stack, AI-powered applications with Cloudflare Workers. Vectorize makes querying embeddings — representations of values or objects like text, images, audio that are designed to be consumed by machine learning models and semantic search algorithms — faster, easier and more affordable.

In this post, we dive deep into how we built Vectorize on Cloudflare’s Developer Platform, leveraging Cloudflare’s global network, Cache, Workers, R2, Queues, Durable Objects, and container platform.

What is a vector database?

A vector database is a queryable store of vectors. A vector is a large array of numbers called vector dimensions.

A vector database has a similarity search query: given an input vector, it returns the vectors that are closest according to a specified metric, potentially filtered on their metadata.

Vector databases are used to power semantic search, document classification, and recommendation and anomaly detection, as well as contextualizing answers generated by LLMs (Retrieval Augmented Generation, RAG).

Why do vectors require special database support?

Conventional data structures like B-trees, or binary search trees expect the data they index to be cheap to compare and to follow a one-dimensional linear ordering. They leverage this property of the data to organize it in a way that makes search efficient. Strings, numbers, and booleans are examples of data featuring this property.

Because vectors are high-dimensional, ordering them in a one-dimensional linear fashion is ineffective for similarity search, as the resulting ordering doesn’t capture the proximity of vectors in the high-dimensional space. This phenomenon is often referred to as the curse of dimensionality.

In addition to this, comparing two vectors using distance metrics useful for similarity search is a computationally expensive operation, requiring vector-specific techniques for databases to overcome.

Query processing architecture

Vectorize builds upon Cloudflare’s global network to bring fast vector search close to its users, and relies on many components to do so.

These are the Vectorize components involved in processing vector queries.


Vectorize runs in every Cloudflare data center, on the infrastructure powering Cloudflare Workers. It serves traffic coming from Worker bindings as well as from the Cloudflare REST API through our API Gateway.

Each query is processed on a server in the data center in which it enters, picked in a fashion that spreads the load across all servers of that data center.

The Vectorize DB Service (a Rust binary) running on that server processes the query by reading the data for that index on R2, Cloudflare’s object storage. It does so by reading through Cloudflare’s Cache to speed up I/O operations.

Searching vectors, and indexing them to speed things up

Being a vector database, Vectorize features a similarity search query: given an input vector, it returns the K vectors that are closest according to a specified metric.

Conceptually, this similarity search consists of 3 steps:

  1. Evaluate the proximity of the query vector with every vector present in the index.

  2. Sort the vectors based on their proximity “score”.

  3. Return the top matches.

While this method is accurate and effective, it is computationally expensive and does not scale well to indexes containing millions of vectors (see Why do vectors require special database support? above).

To do better, we need to prune the search space, that is, avoid scanning the entire index for every query.

For this to work, we need to find a way to discard vectors we know are irrelevant for a query, while focusing our efforts on those that might be relevant.

Indexing vectors with IVF

Vectorize prunes the search space for a query using an indexing technique called IVF, Inverted File Index.

IVF clusters the index vectors according to their relative proximity. For each cluster, it then identifies its centroid, the center of gravity of that cluster, a high-dimensional point minimizing the distance with every vector in the cluster.


Once the list of centroids is determined, each centroid is given a number. We then structure the data on storage by placing each vector in a file named like the centroid it is closest to.

When processing a query, we then can then focus on relevant vectors by looking only in the centroid files closest to that query vector, effectively pruning the search space.


Compressing vectors with PQ

Vectorize supports vectors of up to 1536 dimensions. At 4 bytes per dimension (32 bits float), this means up to 6 KB per vector. That’s 6 GB of uncompressed vector data per million vectors that we need to fetch from storage and put in memory.

To process multi-million vector indexes while limiting the CPU, memory, and I/O required to do so, Vectorize uses a dimensionality reduction technique called PQ (Product Quantization). PQ compresses the vectors data in a way that retains most of their specificity while greatly reducing their size — a bit like down sampling a picture to reduce the file size, while still being able to tell precisely what’s in the picture — enabling Vectorize to efficiently perform similarity search on these lighter vectors.

In addition to storing the compressed vectors, their original data is retained on storage as well, and can be requested through the API; the compressed vector data is used only to speed up the search.

Approximate nearest neighbor search and result accuracy refining

By pruning the search space and compressing the vector data, we’ve managed to increase the efficiency of our query operation, but it is now possible to produce a set of matches that is different from the set of true closest matches. We have traded result accuracy for speed by performing an approximate nearest neighbor search, reaching an accuracy of ~80%.

To boost the result accuracy up to over 95%, Vectorize then performs a result refinement pass on the top approximate matches using uncompressed vector data, and returns the best refined matches.

Eventual consistency and snapshot versioning

Whenever you query your Vectorize index, you are guaranteed to receive results which are read from a consistent, immutable snapshot — even as you write to your index concurrently. Writes are applied in strict order of their arrival in our system, and they are funneled into an asynchronous process. We update the index files by reading the old version, making changes, and writing this updated version as a new object in R2. Each index file has its own version number, and can be updated independently of the others. Between two versions of the index we may update hundreds or even thousands of IVF and metadata index files, but even as we update the files, your queries will consistently use the current version until it is time to switch.

Each IVF and metadata index file has its own version. The list of all versioned files which make up the snapshotted version of the index is contained within a manifest file. Each version of the index has its own manifest. When we write a new manifest file based on the previous version, we only need to update references to the index files which were modified; if there are files which weren’t modified, we simply keep the references to the previous version.

We use a root manifest as the authority of the current version of the index. This is the pivot point for changes. The root manifest is a copy of a manifest file from a particular version, which is written to a deterministic location (the root of the R2 bucket for the index). When our async write process has finished processing vectors, and has written all new index files to R2, we commit by overwriting the current root manifest with a copy of the new manifest. PUT operations in R2 are atomic, so this effectively makes our updates atomic. Once the manifest is updated, Vectorize DB Service instances running on our network will pick it up, and use it to serve reads.

Because we keep past versions of index and manifest files, we effectively maintain versioned snapshots of your index. This means we have a straightforward path towards building a point-in-time recovery feature (similar to D1’s Time Travel feature).

You may have noticed that because our write process is asynchronous, this means Vectorize is eventually consistent — that is, there is a delay between the successful completion of a request writing on the index, and finally seeing those updates reflected in queries.  This isn’t always ideal for all data storage use cases. For example, imagine two users using an online ticket reservation application for airline tickets, where both users buy the same seat — one user will successfully reserve the ticket, and the other will eventually get an error saying the seat was taken, and they need to choose again. Because a vector index is not typically used as a primary database for these transactional use cases, we decided eventual consistency was a worthy trade off in order to ensure Vectorize queries would be fast, high-throughput, and cheap even as the size of indexes grew into the millions.

Coordinating distributed writes: it’s just another block in the WAL

In the section above, we touched on our eventually consistent, asynchronous write process. Now we’ll dive deeper into our implementation. 

The WAL

A write ahead log (WAL) is a common technique for making atomic and durable writes in a database system. Vectorize’s WAL is implemented with SQLite in Durable Objects.

In Vectorize, the payload for each update is given an ID, written to R2, and the ID for that payload is handed to the WAL Durable Object which persists it as a “block.” Because it’s just a pointer to the data, the blocks are lightweight records of each mutation.

Durable Objects (DO) have many benefits — strong transactional guarantees, a novel combination of compute and storage, and a high degree of horizontal scale — but individual DOs are small allotments of memory and compute. However, the process of updating the index for even a single mutation is resource intensive — a single write may include thousands of vectors, which may mean reading and writing thousands of data files stored in R2, and storing a lot of data in memory. This is more than what a single DO can handle.

So we designed the WAL to leverage DO’s strengths and made it a coordinator. It controls the steps of updating the index by delegating the heavy lifting to beefier instances of compute resources (which we call “Executors”), but uses its transactional properties to ensure the steps are done with strong consistency. It safeguards the process from rogue or stalled executors, and ensures the WAL processing continues to move forward. DOs are easy to scale, so we create a new DO instance for each Vectorize index.


WAL Executor

The executors run from a single pool of compute resources, shared by all WALs. We use a simple producer-consumer pattern using Cloudflare Queues. The WAL enqueues a request, and executors poll the queue. When they get a request, they call an API on the WAL requesting to be assigned to the request.

The WAL ensures that one and only one executor is ever assigned to that write. As the executor writes, the index files and the updated manifest are written in R2, but they are not yet visible. The final step is for the executor to call another API on the WAL to commit the change — and this is key — it passes along the updated manifest. The WAL is responsible for overwriting the root manifest with the updated manifest. The root manifest is the pivot point for atomic updates: once written, the change is made visible to Vectorize’s database service, and the updated data will appear in queries.

From the start, we designed this process to account for non-deterministic errors. We focused on enumerating failure modes first, and only moving forward with possible design options after asserting they handled the possibilities for failure. For example, if an executor stalls, the WAL finds a new executor. If the first executor comes back, the coordinator will reject its attempt to commit the update. Even if that first executor is working on an old version which has already been written, and writes new index files and a new manifest to R2, they will not overwrite the files written from the committed version.

Batching updates

Now that we have discussed the general flow, we can circle back to one of our favorite features of the WAL. On the executor, the most time-intensive part of the write process is reading and writing many files from R2. Even with making our reads and writes concurrent to maximize throughput, the cost of updating even thousands of vectors within a single file is dwarfed by the total latency of the network I/O. Therefore it is more efficient to maximize the number of vectors processed in a single execution.

So that is what we do: we batch discrete updates. When the WAL is ready to request work from an executor, it will get a chunk of “blocks” off the WAL, starting with the next un-written block, and maintaining the sequence of blocks. It will write a new “batch” record into the SQLite table, which ties together that sequence of blocks, the version of the index, and the ID of the executor assigned to the batch.

Users can batch multiple vectors to update in a single insert or upsert call. Because the size of each update can vary, the WAL adaptively calculates the optimal size of its batch to increase throughput. The WAL will fit as many upserted vectors as possible into a single batch by counting the number of updates represented by each block. It will batch up to 200,000 vectors at once (a value we arrived at after our own testing) with a limit of 1,000 blocks. With this throughput, we have been able to quickly load millions of vectors into an index (with upserts of 5,000 vectors at a time). Also, the WAL does not pause itself to collect more writes to batch — instead, it begins processing a write as soon as it arrives. Because the WAL only processes one batch at a time, this creates a natural pause in its workflow to batch up writes which arrive in the meantime.

Retraining the index

The WAL also coordinates our process for retraining the index. We occasionally re-train indexes to ensure the mapping of IVF centroids best reflects the current vectors in the index. This maintains the high accuracy of the vector search.

Retraining produces a completely new index. All index files are updated; vectors have been reshuffled across the index space. For this reason, all indexes have a second version stamp — which we call the generation — so that we can differentiate between retrained indexes. 

The WAL tracks the state of the index, and controls when the training is started. We have a second pool of processes called “trainers.” The WAL enqueues a request on a queue, then a trainer picks up the request and it begins training.

Training can take a few minutes to complete, but we do not pause writes on the current generation. The WAL will continue to handle writes as normal. But the training runs from a fixed snapshot of the index, and will become out-of-date as the live index gets updated in parallel. Once the trainer has completed, it signals the WAL, which will then start a multi-step process to switch to the new generation. It enters a mode where it will continue to record writes in the WAL, but will stop making those writes visible on the current index. Then it will begin catching up the retrained index with all of the updates that came in since it started. Once it has caught up to all data present in the index when the trainer signaled the WAL, it will switch over to the newly retrained index. This prevents the new index from appearing to “jump back in time.” All subsequent writes will be applied to that new index.

This is all modeled seamlessly with the batch record. Because it associates the index version with a range of WAL blocks, multiple batches can span the same sequence of blocks as long as they belong to different generations. We can say this another way: a single WAL block can be associated with many batches, as long as these batches are in different generations. Conceptually, the batches act as a second WAL layered over the WAL blocks.

Indexing and filtering metadata

Vectorize supports metadata filters on vector similarity queries. This allows a query to focus the vector similarity search on a subset of the index data, yielding matches that would otherwise not have been part of the top results.

For instance, this enables us to query for the best matching vectors for color: “blue” and category: ”robe”.

Conceptually, what needs to happen to process this example query is:

  • Identify the set of vectors matching color: “blue” by scanning all metadata.

  • Identify the set of vectors matching category: “robe” by scanning all metadata.

  • Intersect both sets (boolean AND in the filter) to identify vectors matching both the color and category filter.

  • Score all vectors in the intersected set, and return the top matches.

While this method works, it doesn’t scale well. For an index with millions of vectors, processing the query that way would be very resource intensive. What’s worse, it prevents us from using our IVF index to identify relevant vector data, forcing us to compute a proximity score on potentially millions of vectors if the filtered set of vectors is large.

To do better, we need to prune the metadata search space by indexing it like we did for the vector data, and find a way to efficiently join the vector sets produced by the metadata index with our IVF vector index.

Indexing metadata with Chunked Sorted List Indexes

Vectorize maintains one metadata index per filterable property. Each filterable metadata property is indexed using a Chunked Sorted List Index.

A Chunked Sorted List Index is a sorted list of all distinct values present in the data for a filterable property, with each value mapped to the set of vector IDs having that value. This enables Vectorize to binary search a value in the metadata index in O(log n) complexity, in other words about as fast as search can be on a large dataset.

Because it can become very large on big indexes, the sorted list is chunked in pieces matching a target weight in KB to keep index state fetches efficient.


A lightweight chunk descriptor list is maintained in the index manifest, keeping track of the list chunks and their lower/upper values. This chunk descriptor list can be binary searched to identify which chunk would contain the searched metadata value.

Once the candidate chunk is identified, Vectorize fetches that chunk from index data and binary searches it to take the set of vector IDs matching a metadata value if found, or an empty set if not found.


We identify the matching vector set this way for every predicate in the metadata filter of the query, then intersect the sets in memory to determine the final set of vectors matched by the filters.

This is just half of the query being processed. We now need to identify the vectors most similar to the query vector, within those matching the metadata filters.

Joining the metadata and vector indexes

A vector similarity query always comes with an input vector. We can rank all centroids of our IVF vector index based on their proximity with that query vector.

The vector set matched by the metadata filters contains for each vector its ID and IVF centroid number.

From this, Vectorize derives the number of vectors matching the query filters per IVF centroid, and determines which and how many top-ranked IVF centroids need to be scanned according to the number of matches the query asks for.

Vectorize then performs the IVF-indexed vector search (see the section Searching Vectors, and indexing them to speed things up above) by considering only the vectors in the filtered metadata vector set while doing so.

Because we’re effectively pruning the vector search space using metadata filters, filtered queries can often be faster than their unfiltered equivalent.

Query performance

The performance of a system is measured in terms of latency and throughput.

Latency is a measure relative to individual queries, evaluating the time it takes for a query to be processed, usually expressed in milliseconds. It is what an end user perceives as the “speed” of the service, so a lower latency is desirable.

Throughput is a measure relative to an index, evaluating the number of queries it can process concurrently over a period of time, usually expressed in requests per second or RPS. It is what enables an application to scale to thousands of simultaneous users, so a higher throughput is desirable.

Vectorize is designed for great index throughput and optimized for low query latency to deliver great performance for demanding applications. Check out our benchmarks.

Query latency optimization

As a distributed database keeping its data state on blob storage, Vectorize’s latency is primarily driven by the fetch of index data, and relies heavily on Cloudflare’s network of caches as well as individual server RAM cache to keep latency low.

Because Vectorize data is snapshot versioned, (see Eventual consistency and snapshot versioning above), each version of the index data is immutable and thus highly cacheable, increasing the latency benefits Vectorize gets from relying on Cloudflare’s cache infrastructure.

To keep the index data lean, Vectorize uses techniques to reduce its weight. In addition to Product Quantization (see Compressing vectors with PQ above), index files use a space-efficient binary format optimized for runtime performance that Vectorize is able to use without parsing, once fetched.

Index data is fragmented in a way that minimizes the amount of data required to process a query. Auxiliary indexes into that data are maintained to limit the amount of fragments to fetch, reducing overfetch by jumping straight to the relevant piece of data on mass storage.

Vectorize boosts all vector proximity computations by leveraging SIMD CPU instructions, and by organizing the vector search in 2 passes, effectively balancing the latency/result accuracy ratio (see Approximate nearest neighbor search and result accuracy refining above).

When used via a Worker binding, each query is processed close to the server serving the worker request, and thus close to the end user, minimizing the network-induced latency between the end user, the Worker application, and Vectorize.

Query throughput

Vectorize runs in every Cloudflare data center, on thousands of servers across the world.

Thanks to the snapshot versioning of every index’s data, every server is simultaneously able to serve the index concurrently, without contention on state.

This means that a Vectorize index elastically scales horizontally with its distributed traffic, providing very high throughput for the most demanding Worker applications.

Increased index size

We are excited that our upgraded version of Vectorize can support a maximum of 5 million vectors, which is a 25x improvement over the limit in beta (200,000 vectors). All the improvements we discussed in this blog post contribute to this increase in vector storage. Improved query performance and throughput comes with this increase in storage as well.

However, 5 million may be constraining for some use cases. We have already heard this feedback. The limit falls out of the constraints of building a brand new globally distributed stateful service, and our desire to iterate fast and make Vectorize generally available so builders can confidently leverage it in their production apps.

We believe builders will be able to leverage Vectorize as their primary vector store, either with a single index or by sharding across multiple indexes. But if this limit is too constraining for you, please let us know. Tell us your use case, and let’s see if we can work together to make Vectorize work for you.

Try it now!

Every developer on a free plan can give Vectorize a try. You can visit our developer documentation to get started.

If you’re looking for inspiration on what to build, see the semantic search tutorial that combines Workers AI and Vectorize for document search, running entirely on Cloudflare. Or an example of how to combine OpenAI and Vectorize to give an LLM more context and dramatically improve the accuracy of its answers.

And if you have questions about how to use Vectorize for our product & engineering teams, or just want to bounce an idea off of other developers building on Workers AI, join the #vectorize and #workers-ai channels on our Developer Discord.

Improving platform resilience at Cloudflare through automation

Post Syndicated from Opeyemi Onikute original https://blog.cloudflare.com/improving-platform-resilience-at-cloudflare

Failure is an expected state in production systems, and no predictable failure of either software or hardware components should result in a negative experience for users. The exact failure mode may vary, but certain remediation steps must be taken after detection. A common example is when an error occurs on a server, rendering it unfit for production workloads, and requiring action to recover.

When operating at Cloudflare’s scale, it is important to ensure that our platform is able to recover from faults seamlessly. It can be tempting to rely on the expertise of world-class engineers to remediate these faults, but this would be manual, repetitive, unlikely to produce enduring value, and not scaling. In one word: toil; not a viable solution at our scale and rate of growth.

In this post we discuss how we built the foundations to enable a more scalable future, and what problems it has immediately allowed us to solve.

Growing pains

The Cloudflare Site Reliability Engineering (SRE) team builds and manages the platform that helps product teams deliver our extensive suite of offerings to customers. One important component of this platform is the collection of servers that power critical products such as Durable Objects, Workers, and DDoS mitigation. We also build and maintain foundational software services that power our product offerings, such as configuration management, provisioning, and IP address allocation systems.

As part of tactical operations work, we are often required to respond to failures in any of these components to minimize impact to users. Impact can vary from lack of access to a specific product feature, to total unavailability. The level of response required is determined by the priority, which is usually a reflection of the severity of impact on users. Lower-priority failures are more common — a server may run too hot, or experience an unrecoverable hardware error. Higher-priority failures are rare and are typically resolved via a well-defined incident response process, requiring collaboration with multiple other teams.

The commonality of lower-priority failures makes it obvious when the response required, as defined in runbooks, is “toilsome”. To reduce this toil, we had previously implemented a plethora of solutions to automate runbook actions such as manually-invoked shell scripts, cron jobs, and ad-hoc software services. These had grown organically over time and provided solutions on a case-by-case basis, which led to duplication of work, tight coupling, and lack of context awareness across the solutions.

We also care about how long it takes to resolve any potential impact on users. A resolution process which involves the manual invocation of a script relies on human action, increasing the Mean-Time-To-Resolve (MTTR) and leaving room for human error. This risks increasing the amount of errors we serve to users and degrading trust.

These problems proved that we needed a way to automatically heal these platform components. This especially applies to our servers, for which failure can cause impact across multiple product offerings. While we have mechanisms to automatically steer traffic away from these degraded servers, in some rare cases the breakage is sudden enough to be visible.

Solving the problem

To provide a more reliable platform, we needed a new component that provides a common ground for remediation efforts. This would remove duplication of work, provide unified context-awareness and increase development speed, which ultimately saves hours of engineering time and effort.

A good solution would not allow only the SRE team to auto-remediate, it would empower the entire company. The key to adding self-healing capability was a generic interface for all teams to self-service and quickly remediate failures at various levels: machine, service, network, or dependencies.

A good way to think about auto-remediation is in terms of workflows. A workflow is a sequence of steps to get to a desired outcome. This is not dissimilar to a manual shell script which executes what a human would otherwise do via runbook instructions. Because of this logical fit with workflows, we decided to adopt Temporal. 

Temporal is a durable execution platform which is useful to gracefully manage infrastructure failures such as network outages and transient failures in external service endpoints. This capability meant we only needed to build a way to schedule “workflow” tasks and have Temporal provide reliability guarantees. This allowed us to focus on building out the orchestration system to support the control and flow of workflow execution in our data centers. 

How does Temporal work?


Before we discuss the system that provides our self-healing functions, let’s explore how the workflow execution engine works, as its native architecture provided numerous benefits that we took advantage of to build a more robust foundation.

The most attractive feature Temporal offered us was the ability to write code that has reliability baked in. Some examples of these primitives are automatic retries, timeouts, rollbacks, and queueing. The Temporal Platform consists of the Temporal Cluster and Worker processes (application code that contains your custom logic).

This architecture allowed us to write our application logic as we normally would, with the added benefits of Temporal. Since Temporal Workers are external to the cluster, we can run tasks anywhere across our global network — a feature that made it easy to build an extensible, easy-to-understand framework for automating tasks.

In Temporal terms, control is provided by the basic principles used to provide workflow execution — Workflows and Activities. A Workflow is simply a sequence of Activities, which are functions that ideally do only ONE task, such as making a request to an external service or rebooting a machine.

Control of workflow behavior can be done using ActivityOptions. This is where you can define timeouts for workflow execution, retry policies, and task queues. Each worker can poll several task queues for both Workflow and Activity tasks. If no worker is polling the task queue in which a Workflow task is declared, nothing happens.

Temporal’s documentation provides a good introduction to writing Temporal workflows.

Building on Temporal

Below, we describe how our automatic remediation system works. It is essentially a way to schedule tasks across our global network with built-in reliability guarantees. With this system, teams can serve their customers more reliably. An unexpected failure mode can be recognized and immediately mitigated, while the root cause can be determined later via a more detailed analysis.

Step one: we need a coordinator


After our initial testing of Temporal, it was now possible to write workflows. But we needed a way to schedule workflow tasks from other internal services. The coordinator was built to serve this purpose, and became the primary mechanism for the authorisation and scheduling of workflows. 

The most important roles of the coordinator are authorisation, workflow task routing, and safety constraints enforcement. Each consumer is authorized via mTLS authentication, and the coordinator uses an ACL to determine whether to permit the execution of a workflow. An ACL configuration looks like the following example.

server_config {
    enable_tls = true
    [...]
    route_rule {
      name  = "global_get"
      method = "GET"
      route_patterns = ["/*"]
      uris = ["spiffe://example.com/worker-admin"]
    }
    route_rule {
      name = "global_post"
      method = "POST"
      route_patterns = ["/*"]
      uris = ["spiffe://example.com/worker-admin"]
      allow_public = true
    }
    route_rule {
      name = "public_access"
      method = "GET"
      route_patterns = ["/metrics"]
      uris = []
      allow_public = true
      skip_log_match = true
    }
}

Each workflow specifies two key characteristics: where to run the tasks and the safety constraints, using an HCL configuration file. Example constraints could be whether to run on only a specific node type (such as a database), or if multiple parallel executions are allowed: if a task has been triggered too many times, that is a sign of a wider problem that might require human intervention. The coordinator uses the Temporal Visibility API to determine the current state of the executions in the Temporal cluster.

An example of a configuration file is shown below:

task_queue_target = "<target>"

# The following entries will ensure that
# 1. This workflow is not run at the same time in a 15m window.
# 2. This workflow will not run more than once an hour.
# 3. This workflow will not run more than 3 times in one day.
#
constraint {
    kind = "concurency"
    value = "1"
    period = "15m"
}

constraint {
    kind = "maxExecution"
    value = "1"
    period = "1h"
}

constraint {
    kind = "maxExecution"
    value = "3"
    period = "24h"
    is_global = true
}

Step two: Task Routing is amazing


An unforeseen benefit of using a central Temporal cluster was the discovery of Task Routing. This feature allows us to schedule a Workflow/Activity on any server that has a running Temporal Worker, and further segment by the type of server, its location, etc. For this reason, we have three primary task queues — the general queue in which tasks can be executed by any worker in the datacenter, the node type queue in which tasks can only be executed by a specific node type in the datacenter, and the individual node queue where we target a specific node for task execution.

We rely on this heavily to ensure the speed and efficiency of automated remediation. Certain tasks can be run in datacenters with known low latency to an external resource, or a node type with better performance than others (due to differences in the underlying hardware). This reduces the amount of failure and latency we see overall in task executions. Sometimes we are also constrained by certain types of tasks that can only run on a certain node type, such as a database.

Task Routing also means that we can configure certain task queues to have a higher priority for execution, although this is not a feature we have needed so far. A drawback of task routing is that every Workflow/Activity needs to be registered to the target task queue, which is a common gotcha. Thankfully, it is possible to catch this failure condition with proper testing.

Step three: when/how to self-heal?

None of this would be relevant if we didn’t put it to good use. A primary design goal for the platform was to ensure we had easy, quick ways to trigger workflows on the most important failure conditions. The next step was to determine what the best sources to trigger the actions were. The answer to this was simple: we could trigger workflows from anywhere as long as they are properly authorized and detect the failure conditions accurately.

Example triggers are an alerting system, a log tailer, a health check daemon, or an authorized engineer via a chatbot. Such flexibility allows a high level of reuse, and permits to invest more in workflow quality and reliability.

As part of the solution, we built a daemon that is able to poll a signal source for any unwanted condition and trigger a configured workflow. We have initially found Prometheus useful as a source because it contains both service-level and hardware/system-level metrics. We are also exploring more event-based trigger mechanisms, which could eliminate the need to use precious system resources to poll for metrics.

We already had internal services that are able to detect widespread failure conditions for our customers, but were only able to page a human. With the adoption of auto-remediation, these systems are now able to react automatically. This ability to create an automatic feedback loop with our customers is the cornerstone of these self-healing capabilities and we continue to work on stronger signals, faster reaction times, and better prevention of future occurrences.

The most exciting part, however, is the future possibility. Every customer cares about any negative impact from Cloudflare. With this platform we can onboard several services (especially those that are foundational for the critical path) and ensure we react quickly to any failure conditions, even before there is any visible impact.

Step four: packaging and deployment

The whole system is written in golang, and a single binary can implement each role. We distribute it as an apt package or a container for maximum ease of deployment.

We deploy a Temporal-based worker to every server we intend to run tasks on, and a daemon in datacenters where we intend to automatically trigger workflows based on the local conditions. The coordinator is more nuanced since we rely on task routing and can trigger from a central coordinator, but we have also found value in running coordinators locally in the datacenters. This is especially useful in datacenters with less capacity or degraded performance, removing the need for a round-trip to schedule the workflows.

Step five: test, test, test

Temporal provides native mechanisms to test an entire workflow, via a comprehensive test suite that supports end-to-end, integration, and unit testing, which we used extensively to prevent regressions while developing. We also ensured proper test coverage for all the critical platform components, especially the coordinator.

Despite the ease of written tests, we quickly discovered that they were not enough. After writing workflows, engineers need an environment as close as possible to the target conditions. This is why we configured our staging environments to support quick and efficient testing. These environments receive the latest changes and point to a different (staging) Temporal cluster, which enables experimentation and easy validation of changes.

After a workflow is validated in the staging environment, we can then do a full release to production. It seems obvious, but catching simple configuration errors before releasing has saved us many hours in development/change-related-task time.

Deploying to production

As you can guess from the title of this post, we put this in production to automatically react to server-specific errors and unrecoverable failures. To this end, we have a set of services that are able to detect single-server failure conditions based on analyzed traffic data. After deployment, we have successfully mitigated potential impact by taking any errant single sources of failure out of production.

We have also created a set of workflows to reduce internal toil and improve efficiency. These workflows can automatically test pull requests on target machines, wipe and reset servers after experiments are concluded, and take away manual processes that cost many hours in toil.

Building a system that is maintained by several SRE teams has allowed us to iterate faster, and rapidly tackle long-standing problems. We have set ambitious goals regarding toil elimination and are on course to achieve them, which will allow us to scale faster by eliminating the human bottleneck.

Looking to the future

Our immediate plans are to leverage this system to provide a more reliable platform for our customers and drastically reduce operational toil, freeing up engineering resources to tackle larger-scale problems. We also intend to leverage more Temporal features such as Workflow Versioning, which will simplify the process of making changes to workflows by ensuring that triggered workflows run expected versions. 

 We are also interested in how others are solving problems using durable execution platforms such as Temporal, and general strategies to eliminate toil. If you would like to discuss this further, feel free to reach out on the Cloudflare Community and start a conversation!

If you’re interested in contributing to projects that help build a better Internet, our engineering teams are hiring.

Leveraging RAG-powered LLMs for Analytical Tasks

Post Syndicated from Grab Tech original https://engineering.grab.com/transforming-the-analytics-landscape-with-RAG-powered-LM

Introduction

Retrieval-Augmented Generation (RAG) is a powerful process that is designed to integrate direct function calling to answer queries more efficiently by retrieving relevant information from a broad database. In the rapidly evolving business landscape, Data Analysts (DAs) are struggling with the growing number of data queries from stakeholders. The conventional method of manually writing and running similar queries repeatedly is time-consuming and inefficient. This is where RAG-powered Large Language Models (LLMs) step in, offering a transformative solution to streamline the analytics process and empower DAs to focus on higher value tasks.

In this article, we will share how the Integrity Analytics team has built out a data solution using LLMs to help automate tedious analytical tasks like generating regular metric reports and performing fraud investigations.

While LLMs are known for their proficiency in data interpretation and insight generation, they represent just a fragment of the entire solution. For a comprehensive solution, LLMs must be integrated with other essential tools. The following is required in assembling a solution:

  • Internally facing LLM tool – Spellvault is a platform within Grab that stores, shares, and refines LLM prompts. It features low/no-code RAG capabilities that lower the barrier of entry for people to create LLM applications.
  • Data – with real time or close to real-time latency to ensure accuracy. It has to be in a standardised format to ensure that all LLM data inputs are accurate.
  • Scheduler – runs LLM applications at regular intervals. Useful for automating routine tasks.
  • Messaging Tool – a user interface where users can interact with LLM by entering a command to receive reports and insights.

Introducing Data-Arks, the data middleware serving up relevant data to the LLM agents

For most data use cases, DAs are usually running the same set of SQL queries with minor changes to parameters like dates, age or other filter conditions. In most instances, we already have a clear understanding of the required data and format to accomplish a task. Therefore, we need a tool that can execute the exact SQL query and channel the data output to the LLM.

Figure 1. Data-Arks hosts various APIs which can be called to serve data to applications like SpellVault.

What is Data-Arks?

Data-Arks is an in-house Python-based API platform housing several frequently used SQL queries and python functions packaged into individual APIs. Data-Arks is also integrated with Slack, Wiki, and JIRA APIs, allowing users to parse and fetch information and data from these tools as well. The benefits of Data-Arks are summarised as follows:

  • Integration: Data-Arks service allows users to upload any SQL query or Python script on the platform. These queries are then surfaced as APIs, which can be called to serve data to the LLM agent.

  • Versatility: Data-Arks can be extended to everyone. Employees from various teams and functions at Grab can self-serve to upload any SQL query that they want onto the platform, allowing this tool to be used for different teams’ use cases.

Automating regular report generation and summarisation using Data-Arks and Spellvault

LLMs are just one piece of the puzzle, to build a comprehensive solution, they must be integrated with other tools. Figure 2 shows how different tools are used in executing report summaries in Slack.

Figure 2 shows how different tools are used in executing report summaries in Slack.

Figure 2. Report Summarizer uses various tools to summarise queries and deliver a summarised report through Slack.

Figure 3 is an example of a summarised report generated by the Report Summarizer using dummy data. Report Summarizer calls a Data-Arks API to generate the data in a tabular format and LLM helps summarise and generate a short paragraph of key insights. This automated report generation has helped save an estimated 3-4 hours per report.

Figure 3. Sample of a report generated using dummy data extracted from [https://data.gov.my/](https://data.gov.my/).

LLM bots for fraud investigations

LLMs also excel in helping to streamline fraud investigations, as LLMs are able to contextualise several different data points and information and derive useful insights from them.

Introducing A* bot, the team’s very own LLM fraud investigation helper.

A set of frequently used queries for fraud investigation is made available as Data-Arks APIs. Upon a user prompt or query, SpellVault selects the most relevant queries using RAG, executes them and provides a summary of the results to users through Slack.

Figure 4. A* bot uses Data-Arks and Spellvault to get information for fraud investigations.

Figure 5 shows a sample of fraud investigation responses from A* bot. Scaling to multiple queries for a fraud investigation process, what was once a time-consuming fraud investigation can now be reduced to a matter of minutes, as the A* bot is capable of providing all the necessary information simultaneously.

Figure 5. Sample of fraud investigation responses.

RAG vs fine-tuning

On deciding between RAG or fine-tuning to improve LLM accuracy, three key factors tipped the scales in favour of the RAG approach:

  • Effort and cost considerations
    Fine-tuning requires significant computational cost as it involves taking a base model and further training it with smaller, domain specific data and context. RAG is computationally less expensive as it relies on retrieving only relevant data and context to augment a model’s response. As the same base model can be used for different use cases, RAG is the preferred choice due to its flexibility and cost efficiency.

  • Ability to respond with the latest information
    Fine-tuning requires model re-training with each new information update, whereas RAG simply retrieves required context and data from a knowledge base to enhance its response. Thus, by using RAG, LLM is able to answer questions using the most current information from our production database, eliminating the need for model re-training.

  • Speed and scalability
    Without the burden of model re-training, the team can rapidly scale and build out new LLM applications with a well managed knowledge base.

What’s next?

The potential of using RAG-powered LLM can be limitless as the ability of GPT is correlated with the tools it equips. Hence, the process does not stop here and we will try to onboard more tools or integration to GPT. In the near future, we plan to utilise Data-Arks to provide images to GPT as GPT-4o is a multimodal model that has vision capabilities. We are committed to pushing the boundaries of what’s possible with RAG-powered LLM, and we look forward to unveiling the exciting advancements that lie ahead.

Figure 6. What’s next?

We would like to express our sincere gratitude to the following individuals and teams whose invaluable support and contributions have made this project a reality:
– Meichen Lu, a senior data scientist at Grab, for her guidance and assistance in building the MVP and testing the concept.
– The data engineering team, particularly Jia Long Loh and Pu Li, for setting up the necessary services and infrastructure.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
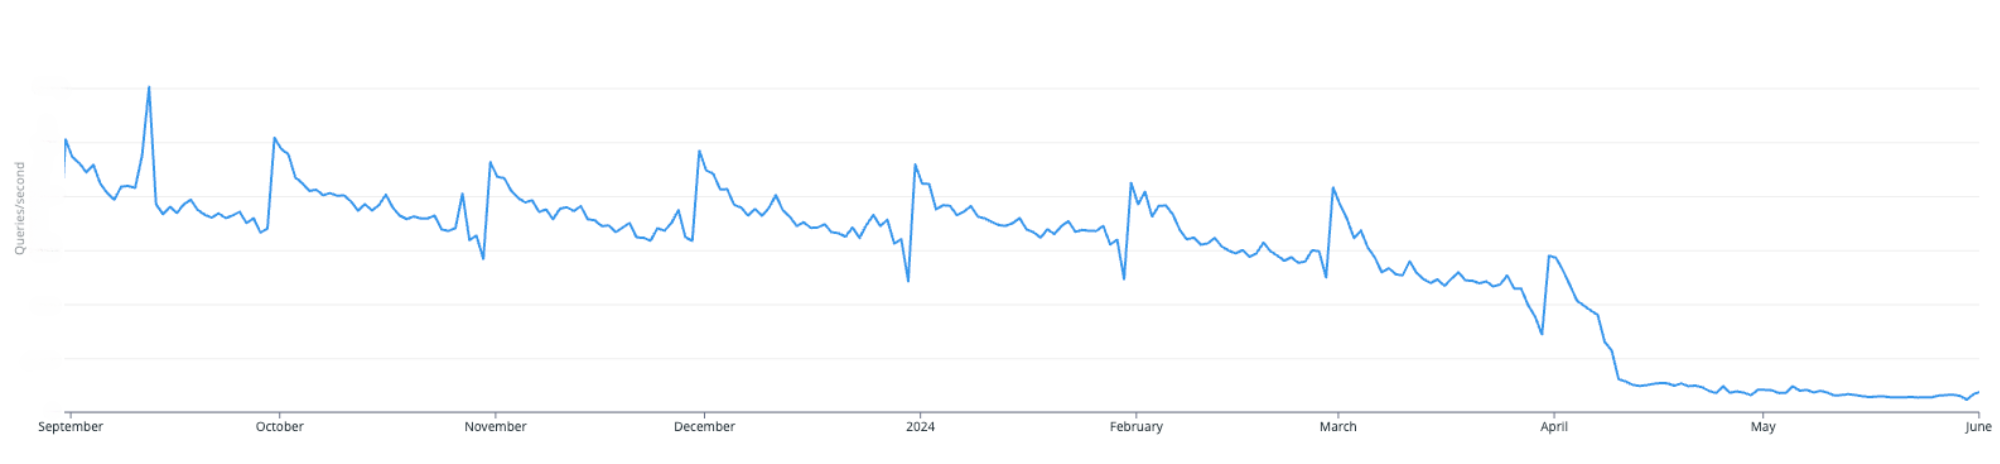
Leveraging RAG-powered LLMs for Analytical Tasks

Post Syndicated from Grab Tech original https://engineering.grab.com/transforming-the-analytics-landscape-with-RAG-powered-LLM

Introduction

Retrieval-Augmented Generation (RAG) is a powerful process that is designed to integrate direct function calling to answer queries more efficiently by retrieving relevant information from a broad database. In the rapidly evolving business landscape, Data Analysts (DAs) are struggling with the growing number of data queries from stakeholders. The conventional method of manually writing and running similar queries repeatedly is time-consuming and inefficient. This is where RAG-powered Large Language Models (LLMs) step in, offering a transformative solution to streamline the analytics process and empower DAs to focus on higher value tasks.

In this article, we will share how the Integrity Analytics team has built out a data solution using LLMs to help automate tedious analytical tasks like generating regular metric reports and performing fraud investigations.

While LLMs are known for their proficiency in data interpretation and insight generation, they represent just a fragment of the entire solution. For a comprehensive solution, LLMs must be integrated with other essential tools. The following is required in assembling a solution:

  • Internally facing LLM tool – Spellvault is a platform within Grab that stores, shares, and refines LLM prompts. It features low/no-code RAG capabilities that lower the barrier of entry for people to create LLM applications.
  • Data – with real time or close to real-time latency to ensure accuracy. It has to be in a standardised format to ensure that all LLM data inputs are accurate.
  • Scheduler – runs LLM applications at regular intervals. Useful for automating routine tasks.
  • Messaging Tool – a user interface where users can interact with LLM by entering a command to receive reports and insights.

Introducing Data-Arks, the data middleware serving up relevant data to the LLM agents

For most data use cases, DAs are usually running the same set of SQL queries with minor changes to parameters like dates, age or other filter conditions. In most instances, we already have a clear understanding of the required data and format to accomplish a task. Therefore, we need a tool that can execute the exact SQL query and channel the data output to the LLM.

Figure 1. Data-Arks hosts various APIs which can be called to serve data to applications like SpellVault.

What is Data-Arks?

Data-Arks is an in-house Python-based API platform housing several frequently used SQL queries and python functions packaged into individual APIs. Data-Arks is also integrated with Slack, Wiki, and JIRA APIs, allowing users to parse and fetch information and data from these tools as well. The benefits of Data-Arks are summarised as follows:

  • Integration: Data-Arks service allows users to upload any SQL query or Python script on the platform. These queries are then surfaced as APIs, which can be called to serve data to the LLM agent.

  • Versatility: Data-Arks can be extended to everyone. Employees from various teams and functions at Grab can self-serve to upload any SQL query that they want onto the platform, allowing this tool to be used for different teams’ use cases.

Automating regular report generation and summarisation using Data-Arks and Spellvault

LLMs are just one piece of the puzzle, to build a comprehensive solution, they must be integrated with other tools. Figure 2 shows how different tools are used in executing report summaries in Slack.

Figure 2 shows how different tools are used in executing report summaries in Slack.

Figure 2. Report Summarizer uses various tools to summarise queries and deliver a summarised report through Slack.

Figure 3 is an example of a summarised report generated by the Report Summarizer using dummy data. Report Summarizer calls a Data-Arks API to generate the data in a tabular format and LLM helps summarise and generate a short paragraph of key insights. This automated report generation has helped save an estimated 3-4 hours per report.

Figure 3. Sample of a report generated using dummy data extracted from [https://data.gov.my/](https://data.gov.my/).

LLM bots for fraud investigations

LLMs also excel in helping to streamline fraud investigations, as LLMs are able to contextualise several different data points and information and derive useful insights from them.

Introducing A* bot, the team’s very own LLM fraud investigation helper.

A set of frequently used queries for fraud investigation is made available as Data-Arks APIs. Upon a user prompt or query, SpellVault selects the most relevant queries using RAG, executes them and provides a summary of the results to users through Slack.

Figure 4. A* bot uses Data-Arks and Spellvault to get information for fraud investigations.

Figure 5 shows a sample of fraud investigation responses from A* bot. Scaling to multiple queries for a fraud investigation process, what was once a time-consuming fraud investigation can now be reduced to a matter of minutes, as the A* bot is capable of providing all the necessary information simultaneously.

Figure 5. Sample of fraud investigation responses.

RAG vs fine-tuning

On deciding between RAG or fine-tuning to improve LLM accuracy, three key factors tipped the scales in favour of the RAG approach:

  • Effort and cost considerations
    Fine-tuning requires significant computational cost as it involves taking a base model and further training it with smaller, domain specific data and context. RAG is computationally less expensive as it relies on retrieving only relevant data and context to augment a model’s response. As the same base model can be used for different use cases, RAG is the preferred choice due to its flexibility and cost efficiency.

  • Ability to respond with the latest information
    Fine-tuning requires model re-training with each new information update, whereas RAG simply retrieves required context and data from a knowledge base to enhance its response. Thus, by using RAG, LLM is able to answer questions using the most current information from our production database, eliminating the need for model re-training.

  • Speed and scalability
    Without the burden of model re-training, the team can rapidly scale and build out new LLM applications with a well managed knowledge base.

What’s next?

The potential of using RAG-powered LLM can be limitless as the ability of GPT is correlated with the tools it equips. Hence, the process does not stop here and we will try to onboard more tools or integration to GPT. In the near future, we plan to utilise Data-Arks to provide images to GPT as GPT-4o is a multimodal model that has vision capabilities. We are committed to pushing the boundaries of what’s possible with RAG-powered LLM, and we look forward to unveiling the exciting advancements that lie ahead.

Figure 6. What’s next?

We would like to express our sincere gratitude to the following individuals and teams whose invaluable support and contributions have made this project a reality:
– Meichen Lu, a senior data scientist at Grab, for her guidance and assistance in building the MVP and testing the concept.
– The data engineering team, particularly Jia Long Loh and Pu Li, for setting up the necessary services and infrastructure.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
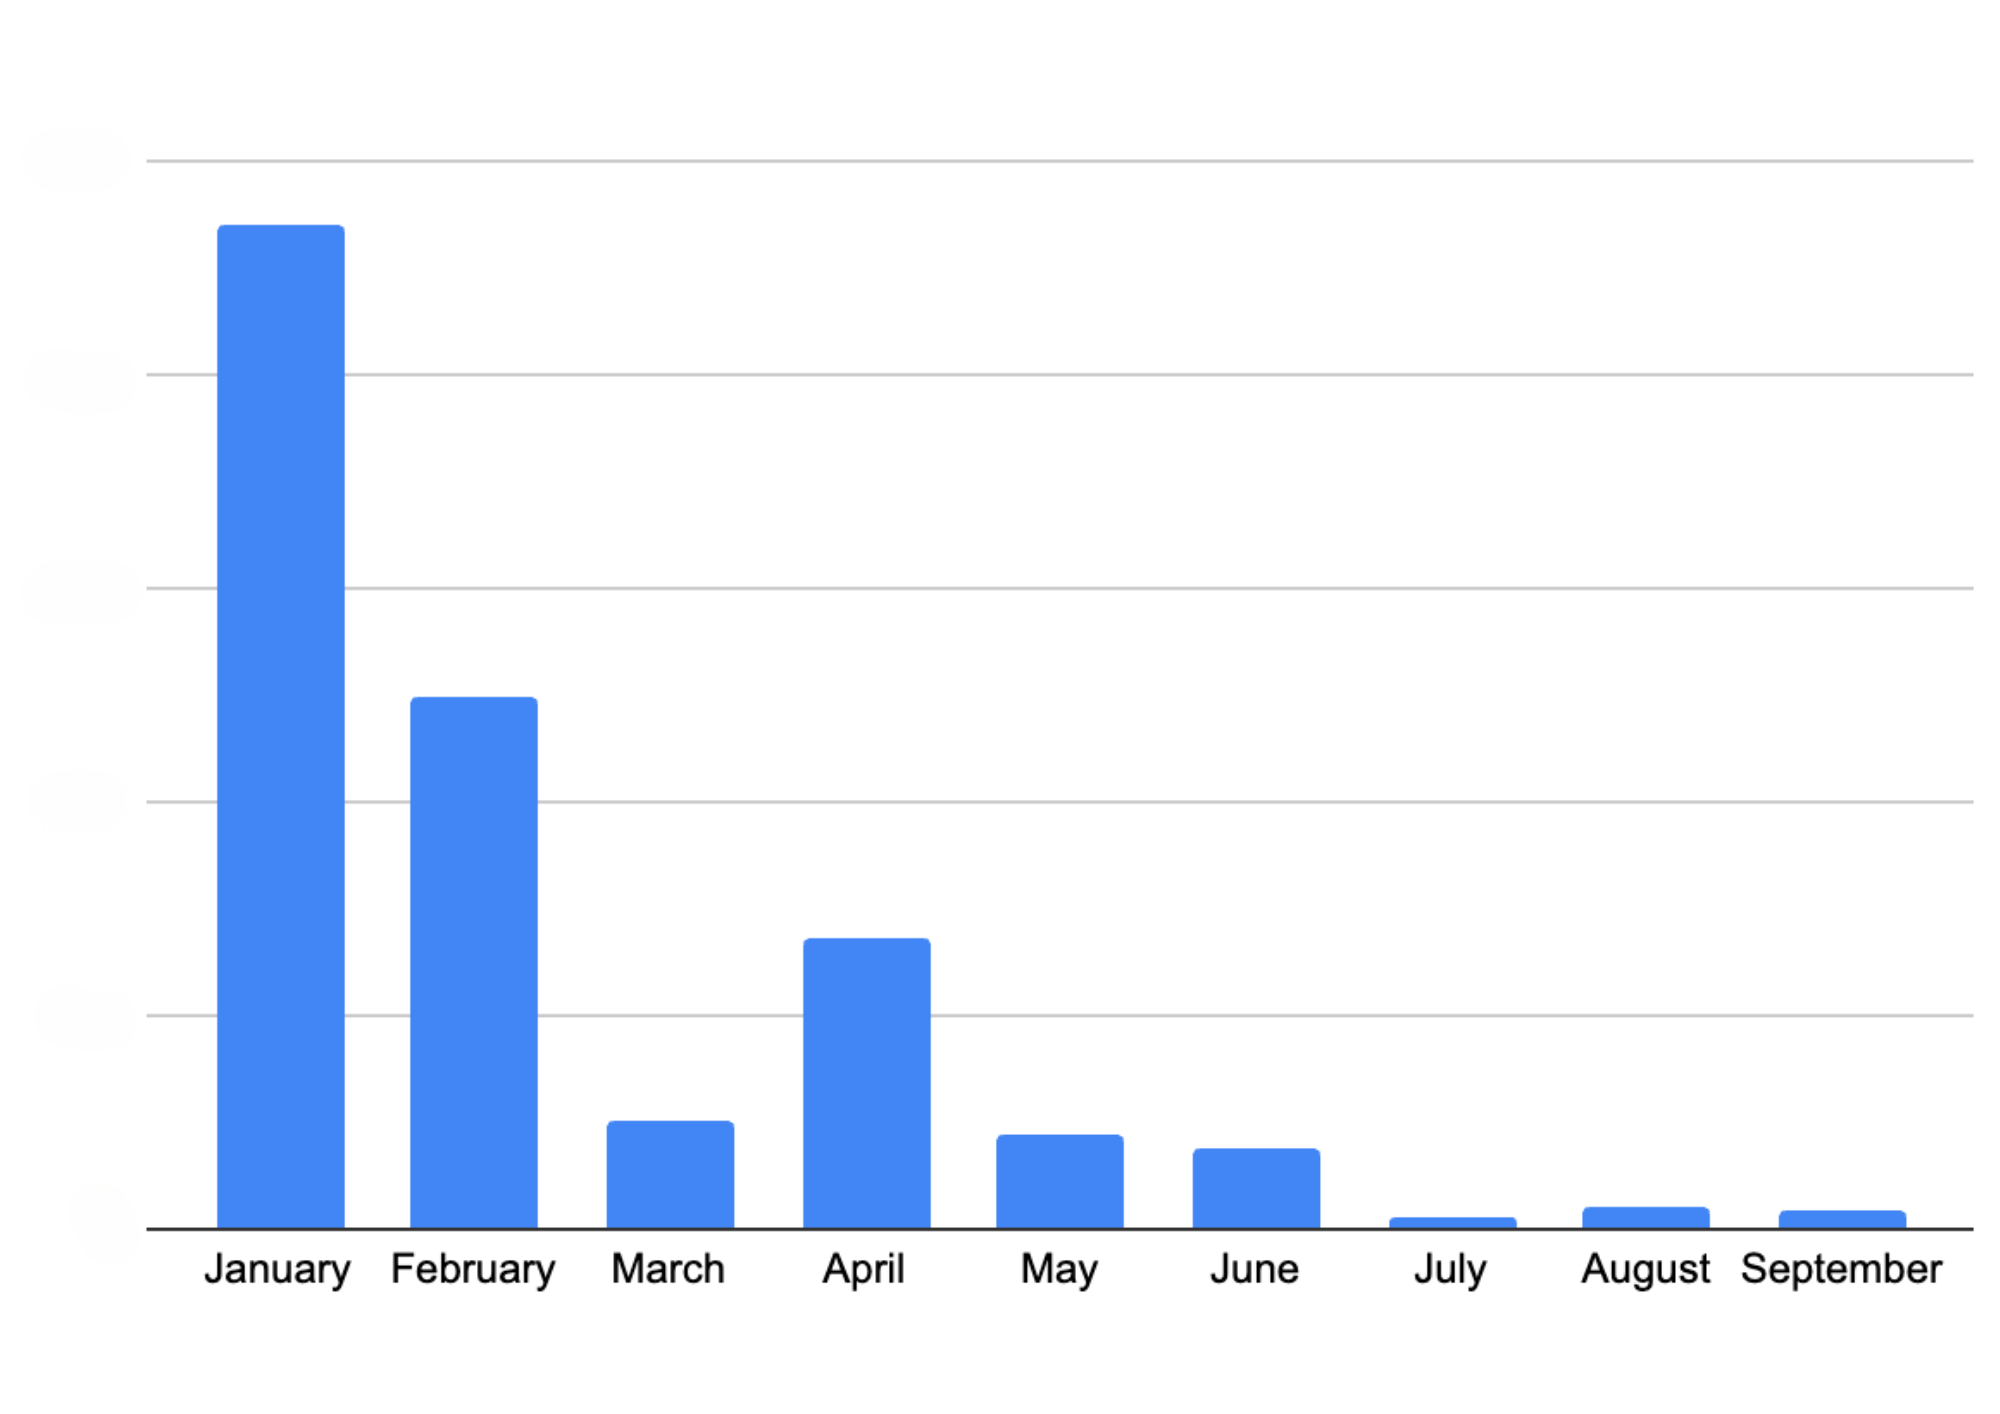
Evolution of Catwalk: Model serving platform at Grab

Post Syndicated from Grab Tech original https://engineering.grab.com/catwalk-evolution

Introduction

As Southeast Asia’s leading super app, Grab serves millions of users across multiple countries every day. Our services range from ride-hailing and food delivery to digital payments and much more. The backbone of our operations? Machine Learning (ML) models. They power our real-time decision-making capabilities, enabling us to provide a seamless and personalised experience to our users. Whether it’s determining the most efficient route for a ride, suggesting a food outlet based on a user’s preference, or detecting fraudulent transactions, ML models are at the forefront.

However, serving these ML models at Grab’s scale is no small feat. It requires a robust, efficient, and scalable model serving platform, which is where our ML model serving platform, Catwalk, comes in.

Catwalk has evolved over time, adapting to the growing needs of our business and the ever-changing tech landscape. It has been a journey of continuous learning and improvement, with each step bringing new challenges and opportunities.

Evolution of the platform

Phase 0: The need for a model serving platform

Before Catwalk’s debut as our dedicated model serving platform, data scientists across the company employed various ad-hoc approaches to serve ML models. These included:

  • Shipping models online using custom solutions.
  • Relying on backend engineering teams to deploy and manage trained ML models.
  • Embedding ML logic within Go backend services.

These methods, however, led to several challenges, undercovering the need for a unified, company-wide platform for serving machine learning models:

  • Operational overhead: Data scientists often lacked the necessary expertise to handle the operational aspects of their models, leading to service outages.
  • Resource wastage: There was frequently low resource utilisation (e.g., 1%) for data science services, leading to inefficient use of resources.
  • Friction with engineering teams: Differences in release cycles and unclear ownership when code was embedded into backend systems resulted in tension between data scientists and engineers.
  • Reinventing the wheel: Multiple teams independently attempted to solve model serving problems, leading to a duplication of effort.

​​These challenges highlighted the need for a company-wide, centralised platform for serving machine learning models.

Phase 1: No-code, managed platform for TensorFlow Serving models

Our initial foray into model serving was centred around creating a managed platform for deploying TensorFlow Serving models. The process involved data scientists submitting their models to the platform’s engineering admin, who could then deploy the model with an endpoint. Infrastructure and networking were managed using Amazon Elastic Kubernetes Service (EKS) and Helm Charts as illustrated below.


This phase of our platform, which we also detailed in our previous article, was beneficial for some users. However, we quickly encountered scalability challenges:

  • Codebase maintenance: Applying changes to every TensorFlow Serving (TFS) version was cumbersome and difficult to maintain.
  • Limited scalability: The fully managed nature of the platform made it difficult to scale.
  • Admin bottleneck: The engineering admin’s limited bandwidth became a bottleneck for onboarding new models.
  • Limited serving types: The platform only supported TensorFlow, limiting its usefulness for data scientists using other frameworks like LightGBM, XGBoost, or PyTorch.

After a year of operation, only eight models were onboarded to the platform, highlighting the need for a more scalable and flexible solution.

Phase 2: From models to model serving applications

To address the limitations of Phase 1, we transitioned from deploying individual models to self-contained model serving applications. This “low-code, self-serving” strategy introduced several new components and changes as illustrated in the points and diagram below:

  • Support for multiple serving types: Users gained the ability to deploy models trained with a variety of frameworks like Open Neural Network Exchange (ONNX), PyTorch, and TensorFlow.
  • Self-served platform through CI/CD pipelines: Data scientists could self-serve and independently manage their model serving applications through CI/CD pipelines.
  • New components: We introduced these new components to support the self-serving approach:
    • Catwalk proxy, a managed reverse proxy to various serving types.
    • Catwalk transformer, a low-code component to transform input and output data.
    • Amphawa, a feature fetching component to augment model inputs.

API request flow

The Catwalk proxy acts as the orchestration layer. Clients send requests to Catwalk proxy then it orchestrates calls to different components like transformers, feature-store, and so on. A typical end to end request flow is illustrated below.


Within a year of implementing these changes, the number of models on the platform increased from 8 to 300, demonstrating the success of this approach. However, new challenges emerged:

  • Complexity of maintaining Helm chart: As the platform continued to grow with new components and functionalities, maintaining the Helm chart became increasingly complex. The readability and flow control became more challenging, making the helm chart updating process prone to errors.
  • Process-level mistakes: The self-serving approach led to errors such as pushing empty or incompatible models to production, setting too few replicas, or allocating insufficient resources, which resulted in service crashes.

We knew that our work was nowhere near done. We had to keep iterating and explore ways to address the new challenges.

Phase 3: Replacing Helm charts with Kubernetes CRDs

To tackle the deployment challenges and gain more control, we made the significant decision to replace Helm charts with Kubernetes Custom Resource Definitions (CRDs). This required substantial engineering effort, but the outcomes have been rewarding. This transition gave us improved control over deployment pipelines, enabling customisations such as:

  • Smart defaults for AutoML
  • Blue-green deployments
  • Capacity management
  • Advanced scaling
  • Application set groupings

Below is an example of a simple model serving CRD manifest:

apiVersion: ml.catwalk.kubebuilder.io/v1
kind: ModelServing
spec:
  hpa:
    desired: 1
    max: 1
    min: 1
  modelMeta:
    modelName: "my-model"
    modelOwner: john.doe
  proxyLayer:
    enableLogging: true
    logHTTPBody: true
  servingLayer:
    servingType: "tensorflow-serving"
    version: "20"

Model serving CRD deployment state machine

Every model serving CRD submission follows a sequence of steps. If there are failures at any step, the controller keeps retrying after small intervals. The major steps on the deployment cycle are described below:

  1. Validate whether the new CRD specs are acceptable. Along with sanity checks, we also enforce a lot of platform constraints through this step.
  2. Clean up previous non-ready deployment resources. Sometimes a deployment submission might keep crashing and hence it doesn’t proceed to a ready state. On every submission, it’s important to check and clean up such previous deployments.
  3. Create resources for the new deployment and ensure that the new deployment is ready.
  4. Switch traffic from old deployment to the new deployment.
  5. Clean up resources for old deployment. At this point, traffic is already being served by the new deployment resources. So, we can clean up the old deployment.

Phase 4: Transition to a high-code, self-served, process-managed platform

As the number of model serving applications and use cases multiplied, clients sought greater control over orchestrations between different models, experiment executions, traffic shadowing, and responses archiving. To cater to these needs, we introduced several changes and components with the Catwalk Orchestrator, a high code orchestration solution, leading the pack.

Catwalk orchestrator

The Catwalk Orchestrator is a highly abstracted framework for building ML applications that replaced the catwalk-proxy from previous phases. The key difference is that users can now write their own business/orchestration logic. The orchestrator offers a range of utilities, reducing the need for users to write extensive boilerplate code. Key components of the Catwalk Orchestrator include HTTP server, gRPC server, clients for different model serving flavours (TensorFlow, ONNX, PyTorch, etc), client for fetching features from the feature bank, and utilities for logging, metrics, and data lake ingestion.

The Catwalk Orchestrator is designed to streamline the deployment of machine learning models. Here’s a typical user journey:

  1. Scaffold a model serving application: Users begin by scaffolding a model serving application using a command-line tool.
  2. Write business logic: Users then write the business logic for the application.
  3. Deploy to staging: The application is then deployed to a staging environment for testing.
  4. Complete load testing: Users test the application in the staging environment and complete load testing to ensure it can handle the expected traffic.
  5. Deploy to production: Once testing is completed, the application is deployed to the production environment.

Bundled deployments

To support multiple ML models as part of a single model serving application, we introduced the concept of bundled deployments. Multiple Kubernetes deployments are bundled together as a single model serving application deployment, allowing each component (e.g., models, catwalk-orchestrator, etc) to have its own Kubernetes deployment and to scale independently.


In addition to the major developments, we implemented other changes to enhance our platform’s efficiency. We made load testing mandatory for all ML application updates to ensure robust performance. This testing process was streamlined with a single command that runs the load test in the staging environment, with the results directly shared with the user.

Furthermore, we boosted deployment transparency by sharing deployment details through Slack and Datadog. This empowered users to diagnose issues independently, reducing the dependency on on-call support. This transparency not only improved our issue resolution times but also enhanced user confidence in our platform.

The results of these changes speak for themselves. The Catwalk Orchestrator has evolved into our flagship product. In just two years, we have deployed 200 Catwalk Orchestrators serving approximately 1,400 ML models.

What’s next?

As we continue to innovate and enhance our model serving platform, we are venturing into new territories:

  • Catwalk serverless: We aim to further abstract the model serving experience, making it even more user-friendly and efficient.
  • Catwalk data serving: We are looking to extend Catwalk’s capabilities to serve data online, providing a more comprehensive service.
  • LLM serving: In line with the trend towards generative AI and large language models (LLMs), we’re pivoting Catwalk to support these developments, ensuring we stay at the forefront of the AI and machine learning field.

Stay tuned as we continue to advance our technology and bring these exciting developments to life.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
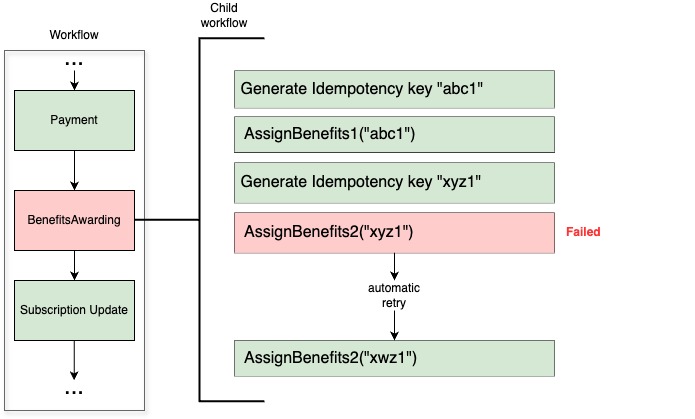
GitHub Enterprise Cloud with data residency: How we built the next evolution of GitHub Enterprise using GitHub

Post Syndicated from Jim Wang original https://github.blog/engineering/engineering-principles/github-enterprise-cloud-with-data-residency/


Today, we announced that GitHub Enterprise Cloud will offer data residency, starting with the European Union (EU) on October 29, 2024, to address a critical desire from customers and enable an optimal, unified experience on GitHub for our customers.

Data residency and what it means for developers

We’ve heard for years from enterprises that being able to control where their data resides is critical for them. With data residency, organizations can now store their GitHub code and repository data in their preferred geographical region. With this need met, even more developers across the globe can build on the world’s AI-powered developer platform.

Enterprise Cloud with data residency provides enhanced user control and unique namespaces on ghe.com isolated from the open source cloud on github.com. It’s built on the security, business continuity, and disaster recovery capabilities of Microsoft Azure.

Image of a Contoso repository displaying a unique namespace which is magnified.

This is a huge milestone for our customers and for GitHub–a multi-year effort that required extensive time, effort, and dedication across the company. We’re excited to share a behind-the-scenes look at how we leveraged GitHub to develop the next evolution of Enterprise Cloud.

Designing the architecture for the next evolution of GitHub Enterprise

This effort started in summer of 2022 with a proof of concept (PoC) and involved teams across GitHub. We carefully considered which architecture would enable us to be successful. After iterating with different approaches, we decided to build the new offering as a feature set that extends Enterprise Cloud. This approach would allow us to be consistently in sync with features on github.com and provide the performance, reliability, and security that our customers expect. For hosting, we effectively leveraged Microsoft Azure’s scale, security, and regional footprint to produce a reliable and secured product with data residency built-in, without having to build new data centers ourselves.

As the home for all developers, developer experience is critically important for us. We recognized early on that consistency was important, so we sought to minimize differences in developing for Enterprise Cloud and Enterprise Cloud with data residency. To this end, the architecture across both is very similar, reducing complexity, risk, and development costs. The deployment model is familiar to our developers: it builds off of GitHub Actions. Also, changes to github.com and Enterprise Cloud with data residency are deployed minutes apart as part of a unified pipeline.

To accomplish this, we had to organize the work, modify our build and deployment systems, and validate the quality of the platform. We were able to do all three of these by using GitHub.

Organizing with GitHub Issues and Projects

To organize the project, we used GitHub Issues and Projects, taking advantage of multiple views to effectively drive work across multiple projects, more than 100 teams, and over 2,000 issues. Different stakeholders and teams could take advantage of these views to focus on the information most relevant to them. Our talented technical project management team helped coordinate updates and used the filtering and slicing capabilities of Projects to present continuously updated information for each milestone in an easily consumable way.

We also used upcoming features like issues hierarchy to help us understand relationships between issues, and issue types to help clearly classify issues across repositories. As part of using these features internally we were able to give feedback to the teams working on them and refine the final product. Keep an eye out for future announcements for issues hierarchy and issue types coming soon!

Image of hierarchies directly inside a GitHub project.

Image of issue types.

All of these powerful features helped us keep the initiative on track. We were able to clearly understand potential risk areas and partner across multiple teams to resolve blockers and complex dependencies, keeping the project effectively moving forward across multiple years.

Building Enterprise Cloud with data residency using GitHub

GitHub has always been built using GitHub. We wanted to continue this practice to set ourselves up for success with the new data residency feature. To this end, we continued leveraging GitHub Codespaces for development and GitHub Actions for continuous integration (CI). In addition, we added deployment targets for new regions. This produced a development, testing, and CI model that required no changes for our developers and a deployment process that was tightly integrated into the existing flow.

We have previously discussed our deploy then merge model, where we deploy branches before merging into the main branch. We expanded this approach to include successful deployments to Enterprise Cloud data residency targets before changes could be merged and considered complete, continuing to use the existing GitHub merge queue. A visualization of our monolithic deployment pipeline is shown in the figure below.

Image showing a visualization of the deployment pipeline.

We start by deploying to environments used by GitHub employees in parallel. This includes the internal environment for Enterprise Cloud with data residency discussed more in the next section. As we use GitHub every day to build GitHub, this step helps us catch issues as employees use the product before it impacts our customers. After automated and manual testing, we proceed to roll out to “Canary.” Canary is the name for the stage where we configure our load balancers to gradually direct an increasing percentage of github.com traffic to the updated version of the code in a staged manner. Additional testing occurs in between each stage. Once we successfully deploy the updated version of github.com to all users, we then deploy and validate Enterprise Cloud with data residency in the EU before finishing the process and merging the pull request.

Ensuring all deployments are successful before we merge means changes are deployed in sync across all Enterprise Cloud environments and monitored effectively. Note that in addition to deployments, we also use feature flags to gradually roll out changes to groups of customers to reduce risk. If a deployment to any target fails, we roll back the change completely. Once we have understood the failure and are ready to deploy again, the entire process starts from the beginning with the merge queue.

Finally, to maintain consistency across all teams and services, we created automation to generate deployment pipelines for over 100 services so, as new targets are introduced, each service automatically deploys to the new environment in a consistent order.

Using Enterprise Cloud with data residency ourselves

To create the best possible product, we also prioritized using it ourselves and stood up an isolated environment for this purpose. Using our GitHub migration tooling, we moved the day-to-day development for the team working on GitHub Enterprise Importer to that environment, and invested in updating our build, deploy, and development environments to support working from the data resident environment. Since its creation, we have deployed to this environment over 8,000 times. This gave us invaluable feedback about the experience of working in the product with issues, pull requests, and actions that we were able to address early in the development process. We were also able to iterate on our status page tooling and internal Service Level Objective (SLO) process with the new environment in mind. The team is continuing to work in this environment today and runs over 1,000 actions jobs a month. This is a testament to the stability and quality we’ve been able to deliver and our commitment to this feature.

What’s next

We are proud that we’ve been able to evolve Enterprise Cloud to offer data residency while using GitHub to organize, build, deploy, and test it. We’re excited to unlock GitHub for even more developers and for you to experience what we have built, starting on October 29, 2024 in the EU, with more regions on the way.

If you’re excited about Enterprise Cloud with data residency, please join us at GitHub Universe 2024 to learn more and hear from other companies how they’ve used this to accelerate software development and innovation.

The post GitHub Enterprise Cloud with data residency: How we built the next evolution of GitHub Enterprise using GitHub appeared first on The GitHub Blog.

Bringing Grab’s Live Activity to Android: Enhancing user experience through custom notifications

Post Syndicated from Grab Tech original https://engineering.grab.com/live-activity-2

In May 2023, Grab unveiled the Live Activity feature for iOS, which received positive feedback from users. Live Activity is a feature that enhances user experience by displaying a user interface (UI) outside of the app, delivering real-time updates and interactive content. At Grab, we leverage this feature to keep users informed about their order updates without requiring them to manually open the app.

While Live Activity is a native iOS feature provided by Apple, there is currently no official Android equivalent. However, we are determined to bring this immersive experience to Android users. Inspired by the success of Live Activity on iOS, we have embarked on design explorations and feasibility studies to ensure the seamless integration of Live Activity into the Android platform. Our ultimate goal is to provide Android users with the same level of convenience and real-time updates, elevating their Grab experience.

Product Exploration

In July 2023, we took a proactive step by forming a dedicated working group with the specific goal of exploring Live Activity on the Android platform. Our mindset was focused on quickly enabling the MVP (Minimum Viable Product) of this feature for Android users. We focused on enabling Grab users to track food and mart orders on Live Activity as our first use-case. We also designed the Live Activity module as an extendable platform, allowing easy adoption by other Grab internal verticals such as the Express and Transport teams.

The team kicked off by analysing the current solution and end-to-end flow of Live Activity on iOS. The objective was to uncover opportunities on how we could leverage the existing platform approach.

Figure 1. Grab iOS Live Activity flow.

The first thing that caught our attention was that there is no Live Activity Token (also known as Push Token) concept on Android. Push Token is a token generated from the ActivityKit framework and used to remotely start, update, and end Live Activity notifications on iOS.

Our goal was to match the Live Activity set-up of iOS in Android, which was a challenge due to the missing Push Token. This required us to think outside the box and develop an innovative workaround. After multiple brainstorming sessions, the team developed two potential solutions, Solution 1 and Solution 2, as illustrated below:

Figure 2. Proposed solutions for Live Activity for Android.

We evaluated the two solutions. The first solution is to substitute the Push Token with a placeholder value, serving as a distinctive notification identifier. Whereas, the second solution involves the Hedwig service, our in-house message delivery service. We proposed to bypass the Live Activity token check process specifically for Android devices. Following extensive discussions, we decided to proceed with the first solution, which ensures consistency in the technical approach between Android and iOS platforms. Additionally, this solution allows us to ensure that notifications are only pushed to the devices that support the Live Activity feature. This decision strikes a good balance between efficiency and compatibility.

UI Components

Starting with a kick-off project meeting where we showcased our plans and proposed solutions to our stakeholders, the engineering team presented two native Android UI components that could be utilised to replicate Live Activity: the Notification View and the Floating View.

The Notification View is a component located in the notification drawer (and potentially on the Lock Screen) that fulfils the most basic use-case of the Live Activity feature. It enables Android users to access information without the need to open the app. Since the standard notification template only allows developers to display a single content title, a content subtitle, and one image, it falls short of meeting our Live Activity UI requirements. To overcome this limitation, custom notifications with custom layouts are needed.

Figure 3. Early design spec of Grab’s LA using custom notification.

One of the key advantages of custom notifications is that they do not require any additional new permissions, ensuring a smooth user experience. Additionally, Android users are accustomed to checking their notifications from the notification tray, making it a familiar and intuitive interaction. However, it is important to acknowledge that custom notifications rely on a remote view, which can pose restrictions on rendering only specific views. On top of that, custom notifications provide a limited space for content – limited to 48dp when collapsed and 252dp when expanded.

The Floating View is a component that will appear above all the applications in Android. It adds the convenience of accessing the information when the device is unlocked or when the user is on another app.

Figure 4. Early design spec of Grab’s LA using floating view.

The use of a Floating View offers greater flexibility to the view by eliminating the reliance on a remote view. However, it’s important to be aware of the potential limitations associated with this approach. These limitations include the requirement for screen space, which can potentially impact other app functionalities and cause frustration for users. Additionally, if we intend to display multiple order updates, we may require even more space, taking into account that Grab allows users to place multiple orders. Furthermore, the Floating View feature requires an extra “Draw over other apps” permission, a setting that allows an app to display information on top of other apps on your screen.

After thoughtful deliberation, we concluded that custom notifications provide a more consistent and user-friendly solution for implementing Grab’s Live Activity feature on Android. They offer compatibility, non-intrusiveness, no extra permissions, and the flexibility of silent notifications, ensuring an optimised user experience.

Building Grab Android’s “Live Activity”

We began developing the Live Activity feature by focusing on Food and Mart for the MVP. However, we prioritised potential future use cases for other verticals by examining the existing functionality of the Grab iOS Live Activity feature. By considering these factors from the start, we need to make sure that we build an extendable and flexible solution that caters to different verticals and their various use-cases.

Figure 5. Grab’s Android Live Activity.

As we set out to design Grab’s Android Live Activity module, we broke down the task into three key components:

  1. Registering Live Activity Token

In order to enable Hedwig services to send Live Activity notifications to devices, it is necessary to register a Live Activity Token for a specific order to Grab Devices services (refer to figure 1 for the iOS flow). As this use-case is applicable across various verticals in iOS, we have designed a LiveActivityIntegrationManager class specifically to handle this functionality.

interface LiveActivityIntegrationManager {  
    /\*\*  
     \* To start live activity journey  
     \* @param vertical refers to vertical name  
     \* @param id refers to unique id which is used to differentiate live activity UI instances  
     \* eg: Food will use orderID as id, transport can pass rideID  
     \*\*/  
    fun startLiveActivity(vertical: Vertical, id: String): Completable

    fun updateLiveActivity(id: String, attributes: LiveActivityAttributes)

    fun cancelLiveActivity(id: String)  
}  

Our goal is to provide developers with an easy implementation of Live Activity in the Grab app. Developers can simply utilize the startLiveActivity() function to register the token to Grab Devices by passing the vertical name and unique ID as parameters.

  1. Notification Listener and Payload Mapping

To handle Live Activity notifications in Android, it is necessary to listen to the Live Activity notification payload and map it to LiveActivityAttributes. Taking into consideration the initial Live Activity design (refer to figure 3), we need to analyse the variables necessary for this process. As a result, we break down the Live Activity UI into different UI elements and layouts, as follows:

Figure 6. Android Live Activity view breakdown.
  1. App Icon – labeled as 1 in Figure 6.
    This view always shows the Grab app icon.
  2. Header Icon – labeled as 2 in Figure 6.
    This view is an image view that could be set with icon resources.
  3. Content Title View – labeled as 3 in Figure 6.
    This view is a placeholder that could be set with a text or custom remote view.
  4. Content Text View – labeled as 4 in Figure 6.
    This view is a placeholder that could be set with a text or custom remote view.
  5. Footer View – labeled as 5 in Figure 6.
    This view is a placeholder that could be set with icon resources, bitmap, or custom remote view.

Decomposing the UI into different parts allows us to clearly understand of the UI components that need to maintain consistency across different use-cases, as well as the elements that can be easily customised and configured based on specific requirements. As a result, we have designed the LiveActivityAttributes class that serves as a container that encompasses all the necessary configurations required for rendering the Live Activity.

 
class LiveActivityAttributes private constructor(  
    val iconRes: Int?,  
    val headerIconRes: Int?,  
    val contentTitle: CharSequence?,  
    val contentTitleStyle: ContentStyle.TitleStyle?,  
    val customContentTitleView: LiveActivityCustomView?,  
    val contentText: CharSequence?,  
    val contentTextStyle: ContentStyle.TextStyle?,  
    val customContentTextView: LiveActivityCustomView?,  
    val footerIconRes: Int?,  
    val footerBitmap: Bitmap?,  
    val footerProgressBarProgress: Float?,  
    val footerProgressBarStyle: ProgressBarStyle?,  
    val footerRatingBarAttributes: RatingBarAttributes?,  
    val customFooterView: LiveActivityCustomView?,  
    val contentIntent: PendingIntent?,  
    …  
)  

  1. Payload Rendering

To ensure a clear separation of responsibilities, we have designed a separate class called LiveActivityManager. This dedicated class is responsible for the mapping of LiveActivityAttributes to Notifications. The generated notifications are then utilised by Android’s NotificationManager class to be posted and displayed accordingly.


interface LiveActivityManager {  
    /\*\*  
     \* Post a Live Activity to be shown in the status bar, stream, etc.  
     \*  
     \* @param id           the ID of the Live Activity  
     \* @param attributes the LiveActivity to post to the system  
     \*/  
    fun notify(id: Int, attributes: LiveActivityAttributes)

    fun cancel(id: Int)  
}

What’s Next?

We are delighted to announce that we have successfully implemented Grab’s Android version of the Live Activity feature for Express and Transport products. Furthermore, we plan to extend this feature to the Driver and Merchant applications as well. We understand the value this feature brings to our users and are committed to enhancing it further. Stay tuned for upcoming updates and enhancements to the Live Activity feature as we continue to improve and expand its capabilities across various verticals.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 428 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
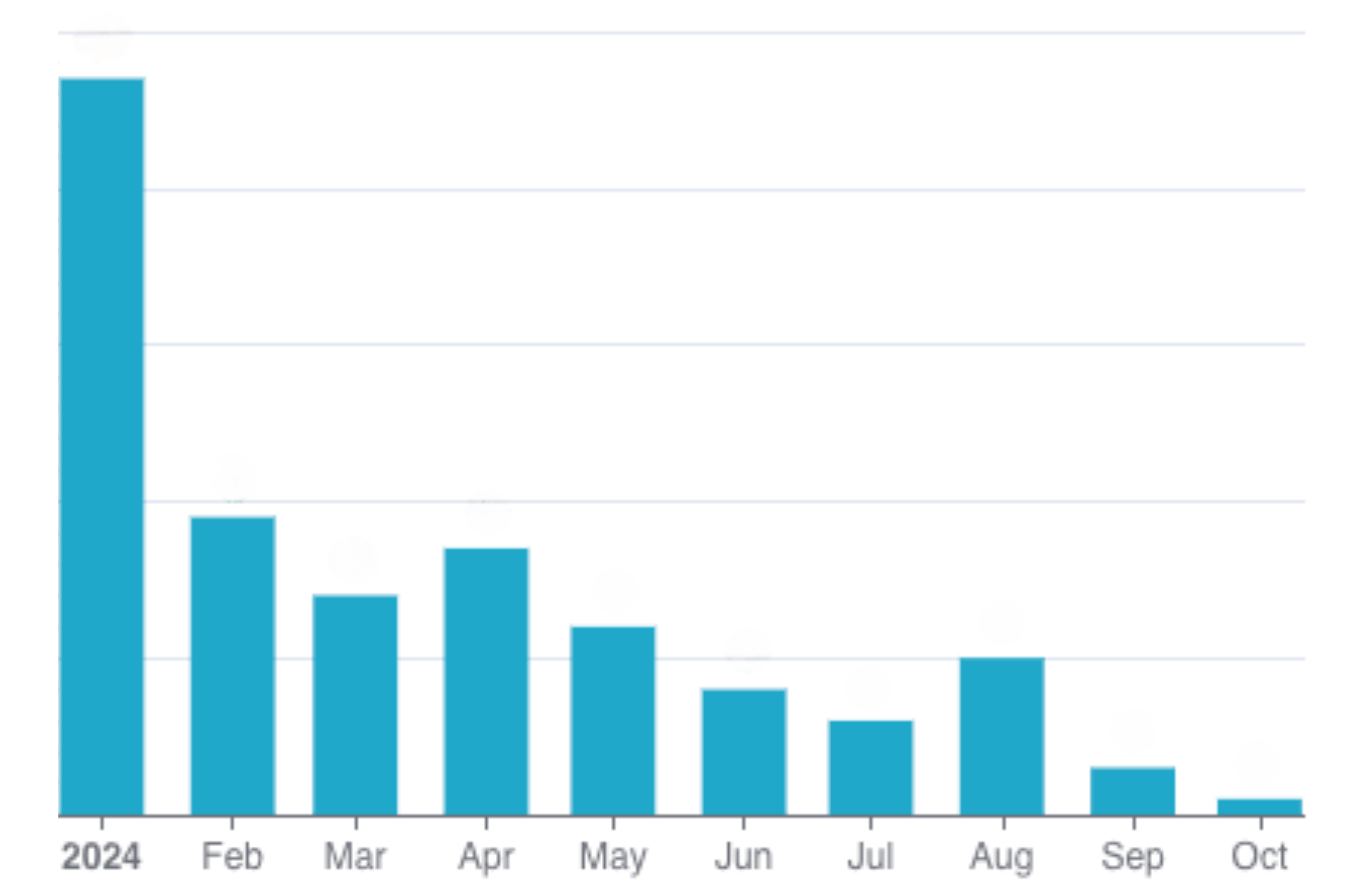
Enabling conversational data discovery with LLMs at Grab

Post Syndicated from Grab Tech original https://engineering.grab.com/hubble-data-discovery

Imagine a world where finding the right data is like searching for a needle in a haystack. In today’s data-driven landscape, companies are drowning in a sea of information, struggling to navigate through countless datasets to uncover valuable insights. At Grab, we faced a similar challenge. With over 200,000 tables in our data lake, along with numerous Kafka streams, production databases, and ML features, locating the most suitable dataset for our Grabber’s use cases promptly has historically been a significant hurdle.

Problem Space

Our internal data discovery tool, Hubble, built on top of the popular open-source platform Datahub, was primarily used as a reference tool. While it excelled at providing metadata for known datasets, it struggled with true data discovery due to its reliance on Elasticsearch, which performs well for keyword searches but cannot accept and use user-provided context (i.e., it can’t perform semantic search, at least in its vanilla form). The Elasticsearch parameters provided by Datahub out of the box also had limitations: our monthly average click-through rate was only 82%, meaning that in 18% of sessions, users abandoned their searches without clicking on any dataset. This suggested that the search results were not meeting their needs.

Another indispensable requirement for efficient data discovery that was missing at Grab was documentation. Documentation coverage for our data lake tables was low, with only 20% of the most frequently queried tables (colloquially referred to as P80 tables) having existing documentation. This made it difficult for users to understand the purpose and contents of different tables, even when browsing through them on the Hubble UI.

Consequently, data consumers heavily relied on tribal knowledge, often turning to their colleagues via Slack to find the datasets they needed. A survey conducted last year revealed that 51% of data consumers at Grab took multiple days to find the dataset they required, highlighting the inefficiencies in our data discovery process.

To address these challenges and align with Grab’s ongoing journey towards a data mesh architecture, the Hubble team recognised the importance of improving data discovery. We embarked on a journey to revolutionise the way our employees find and access the data they need, leveraging the power of AI and Large Language Models (LLMs).

Vision

Given the historical context, our vision was clear: to remove humans in the data discovery loop by automating the entire process using LLM-powered products. We aimed to reduce the time taken for data discovery from multiple days to mere seconds, eliminating the need for anyone to ask their colleagues data discovery questions ever again.


Goals

To achieve our vision, we set the following goals for ourselves for the first half of 2024:

  • Build HubbleIQ: An LLM-based chatbot that could serve as the equivalent of a Lead Data Analyst for data discovery. Just as a lead is an expert in their domain and can guide data consumers to the right dataset, we wanted HubbleIQ to do the same across all domains at Grab. We also wanted HubbleIQ to be accessible where data consumers hang out the most: Slack.
  • Improve documentation coverage: A new Lead Analyst joining the team would require extensive documentation coverage of very high quality. Without this, they wouldn’t know what data exists and where. Thus, it was important for us to improve documentation coverage.
  • Enhance Elasticsearch: We aimed to tune our Elasticsearch implementation to better meet the requirements of Grab’s data consumers.

A Systematic Path to Success

Step 1: Enhance Elasticsearch

Through clickstream analysis and user interviews, the Hubble team identified four categories of data search queries that were seen either on the Hubble UI or in Slack channels:

  • Exact search: Queries belonging to this category were a substring of an existing dataset’s name at Grab, with the query length being at least 40% of the dataset’s name.
  • Partial search: The Levenshtein distance between a query in this category and any existing dataset’s name was greater than 80. This category usually comprised queries that closely resembled an existing dataset name but likely contained spelling mistakes or were shorter than the actual name.

Exact and partial searches accounted for 75% of searches on Hubble (and were non-existent on Slack: as a human, receiving a message that just had the name of a dataset would feel rather odd). Given the effectiveness of vanilla Elasticsearch for these categories, the click rank was close to 0.


  • Inexact search: This category comprised queries that were usually colloquial keywords or phrases that may be semantically related to a given table, column, or piece of documentation (e.g., “city” or “taxi type”). Inexact searches accounted for the remaining 25% of searches on Hubble. Vanilla Elasticsearch did not perform well in this category since it relied on pure keyword matching and did not consider any additional context.

  • Semantic search: These were free text queries with abundant contextual information supplied by the user. Hubble did not see any such queries as users rightly expected that Hubble would not be able to fulfil their search needs. Instead, these queries were sent by data consumers to data producers via Slack. Such queries were numerous, but usually resulted in data hunting journeys that spanned multiple days – the root of frustration amongst data consumers.

The first two search types can be seen as “reference” queries, where the data consumer already knows what they are looking for. Inexact and contextual searches are considered “discovery” queries. The Hubble team noticed drop-offs in inexact searches because users learned that Hubble could not fulfil their discovery needs, forcing them to search for alternatives.

Through user interviews, the team discovered how Elasticsearch should be tuned to better fit the Grab context. They implemented the following optimisations:

  • Tagging and boosting P80 tables
  • Boosting the most relevant schemas
  • Hiding irrelevant datasets like PowerBI dataset tables
  • Deboosting deprecated tables
  • Improving the search UI by simplifying and reducing clutter
  • Adding relevant tags
  • Boosting certified tables

As a result of these enhancements, the click-through rate rose steadily over the course of the half to 94%, a 12 percentage point increase.

While this helped us make significant improvements to the first three search categories, we knew we had to build HubbleIQ to truly automate the last category – semantic search.

Step 2: Build a Context Store for HubbleIQ

To support HubbleIQ, we built a documentation generation engine that used GPT-4 to generate documentation based on table schemas and sample data. We refined the prompt through multiple iterations of feedback from data producers.

We added a “generate” button on the Hubble UI, allowing data producers to easily generate documentation for their tables. This feature also supported the ongoing Grab-wide initiative to certify tables.


In conjunction, we took the initiative to pre-populate docs for the most critical tables, while notifying data producers to review the generated documentation. Such docs were visible to data consumers with an “AI-generated” tag as a precaution. When data producers accepted or edited the documentation, the tag was removed.


As a result, documentation coverage for P80 tables increased by 70 percentage points to ~90%. User feedback showed that ~95% of users found the generated docs useful.

Step 3: Build and Launch HubbleIQ

With high documentation coverage in place, we were ready to harness the power of LLMs for data discovery. To speed up go-to-market, we decided to leverage Glean, an enterprise search tool used by Grab.

First, we integrated Hubble with Glean, making all data lake tables with documentation available on the Glean platform. Next, we used Glean Apps to create the HubbleIQ bot, which was essentially an LLM with a custom system prompt that could access all Hubble datasets that were catalogued on Glean. Finally, we integrated this bot into Hubble search, such that for any search that is likely to be a semantic search, HubbleIQ results are shown on top, followed by regular search results.


Recently, we integrated HubbleIQ with Slack, allowing data consumers to discover datasets without breaking their flow. Currently, we are working with analytics teams to add the bot to their “ask” channels (where data consumers come to ask contextual search queries for their domains). After integration, HubbleIQ will act as the first line of defence for answering questions in these channels, reducing the need for human intervention.


The impact of these improvements was significant. A follow-up survey revealed that 73% of respondents found it easy to discover datasets, marking a substantial 17 percentage point increase from the previous survey. Moreover, Hubble reached an all-time high in monthly active users, demonstrating the effectiveness of the enhancements made to the platform.

Next Steps

We’ve made significant progress towards our vision, but there’s still work to be done. Looking ahead, we have several exciting initiatives planned to further enhance data discovery at Grab.

On the documentation generation front, we aim to enrich the generator with more context, enabling it to produce even more accurate and relevant documentation. We also plan to streamline the process by allowing analysts to auto-update data docs based on Slack threads directly from Slack. To ensure the highest quality of documentation, we will develop an evaluator model that leverages LLMs to assess the quality of both human and AI-written docs. Additionally, we will implement Reflexion, an agentic workflow that utilises the outputs from the doc evaluator to iteratively regenerate docs until a quality benchmark is met or a maximum try-limit is reached.

As for HubbleIQ, our focus will be on continuous improvement. We’ve already added support for metric datasets and are actively working on incorporating other types of datasets as well. To provide a more seamless user experience, we will enable users to ask follow-up questions to HubbleIQ directly on the HubbleUI, with the system intelligently pulling additional metadata when a user mentions a specific dataset.

Conclusion

By harnessing the power of AI and LLMs, the Hubble team has made significant strides in improving documentation coverage, enhancing search capabilities, and drastically reducing the time taken for data discovery. While our efforts so far have been successful, there are still steps to be taken before we fully achieve our vision of completely replacing the reliance on data producers for data discovery. Nonetheless, with our upcoming initiatives and the groundwork we have laid, we are confident that we will continue to make substantial progress in the right direction over the next few production cycles.

As we forge ahead, we remain dedicated to refining and expanding our AI-powered data discovery tools, ensuring that Grabbers have every dataset they need to drive Grab’s success at their fingertips. The future of data discovery at Grab is brimming with possibilities, and the Hubble team is thrilled to be at the forefront of this exciting journey.

To our readers, we hope that our journey has inspired you to explore how you can leverage the power of AI to transform data discovery within your own organisations. The challenges you face may be unique, but the principles and strategies we have shared can serve as a foundation for your own data discovery revolution. By embracing innovation, focusing on user needs, and harnessing the potential of cutting-edge technologies, you too can unlock the full potential of your data and propel your organisation to new heights. The future of data-driven innovation is here, and we invite you to join us on this exhilarating journey.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Unveiling the process: The creation of our powerful campaign builder

Post Syndicated from Grab Tech original https://engineering.grab.com/the-creation-of-our-powerful-campaign-builder

In a previous blog, we introduced Trident, Grab’s internal marketing campaign platform. Trident empowers our marketing team to configure If This, Then That (IFTTT) logic and processes real-time events based on that.

While we mainly covered how we scaled up the system to handle large volumes of real-time events, we did not explain the implementation of the event processing mechanism. This blog will fill up this missing piece. We will walk you through the various processing mechanisms supported in Trident and how they were built.

Base building block: Treatment

In our system, we use the term “treatment” to refer to the core unit of a full IFTTT data structure. A treatment is an amalgamation of three key elements – an event, conditions (which are optional), and actions. For example, consider a promotional campaign that offers “100 GrabPoints for completing a ride paid with GrabPay Credit”. This campaign can be transformed into a treatment in which the event is “ride completion”, the condition is “payment made using GrabPay Credit”, and the action is “awarding 100 GrabPoints”.

Data generated across various Kafka streams by multiple services within Grab forms the crux of events and conditions for a treatment. Trident processes these Kafka streams, treating each data object as an event for the treatments. It evaluates the set conditions against the data received from these events. If all conditions are met, Trident then executes the actions.

Figure 1. Trident processes Kafka streams as events for treatments.

When the Trident user interface (UI) was first established, campaign creators had to grasp the treatment concept and configure the treatments accordingly. As we improved the UI, it became more user-friendly.

Building on top of treatment

Campaigns can be more complex than the example we provided earlier. In such scenarios, a single campaign may need transformation into several treatments. All these individual treatments are categorised under what we refer to as a “treatment group”. In this section, we discuss features that we have developed to manage such intricate campaigns.

Counter

Let’s say we have a marketing campaign that “rewards users after they complete 4 rides”. For this requirement, it’s necessary for us to keep track of the number of rides each user has completed. To make this possible, we developed a capability known as counter.

On the backend, a single counter setup translates into two treatments.

Treatment 1:

  • Event: onRideCompleted
  • Condition: N/A
  • Action: incrementUserStats

Treatment 2:

  • Event: onProfileUpdate
  • Condition: Ride Count == 4
  • Action: awardReward

In this feature, we introduce a new event, onProfileUpdate. The incrementUserStats action in Treatment 1 triggers the onProfileUpdate event following the update of the user counter. This allows Treatment 2 to consume the event and perform subsequent evaluations.

Figure 2. The end-to-end evaluation process when using the Counter feature.

When the onRideCompleted event is consumed, Treatment 1 is evaluated which then executes the incrementUserStat action. This action increments the user’s ride counter in the database, gets the latest counter value, and publishes an onProfileUpdate event to Kafka.

There are also other consumers that listen to onProfileUpdate events. When this event is consumed, Treatment 2 is evaluated. This process involves verifying whether the Ride Count equals to 4. If the condition is satisfied, the awardReward action is triggered.

This feature is not limited to counting the number of event occurrences only. It’s also capable of tallying the total amount of transactions, among other things.

Delay

Another feature available on Trident is a delay function. This feature is particularly beneficial in situations where we want to time our actions based on user behaviour. For example, we might want to give a ride voucher to a user three hours after they’ve ordered a ride to a theme park. The intention for this is to offer them a voucher they can use for their return trip.

On the backend, a delay setup translates into two treatments. Given the above scenario, the treatments are as follows:

Treatment 1:

  • Event: onRideCompleted
  • Condition: Dropoff Location == Universal Studio
  • Action: scheduleDelayedEvent

Treatment 2:

  • Event: onDelayedEvent
  • Condition: N/A
  • Action: awardReward

We introduce a new event, onDelayedEvent, which Treatment 1 triggers during the scheduleDelayedEvent action. This is made possible by using Simple Queue Service (SQS), given its built-in capability to publish an event with a delay.

Figure 3. The end-to-end evaluation process when using the Delay feature.

The maximum delay that SQS supports is 15 minutes; meanwhile, our platform allows for a delay of up to x hours. To address this limitation, we publish the event multiple times upon receiving the message, extending the delay by another 15 minutes each time, until it reaches the desired delay of x hours.

Limit

The Limit feature is used to restrict the number of actions for a specific campaign or user within that campaign. This feature can be applied on a daily basis or for the full duration of the campaign.

For instance, we can use the Limit feature to distribute 1000 vouchers to users who have completed a ride and restrict it to only one voucher for one user per day. This ensures a controlled distribution of rewards and prevents a user from excessively using the benefits of a campaign.

In the backend, a limit setup translates into conditions within a single treatment. Given the above scenario, the treatment would be as follows:

  • Event: onRideCompleted
  • Condition: TotalUsageCount <= 1000 AND DailyUserUsageCount <= 1
  • Action: awardReward

Similar to the Counter feature, it’s necessary for us to keep track of the number of completed rides for each user in the database.

Figure 4. The end-to-end evaluation process when using the Limit feature.

A better campaign builder

As our campaigns grew more and more complex, the treatment creation quickly became overwhelming. A complex logic flow often required the creation of many treatments, which was cumbersome and error-prone. The need for a more visual and simpler campaign builder UI became evident.

Our design team came up with a flow-chart-like UI. Figure 5, 6, and 7 show examples of how certain imaginary campaign setup would look like in the new UI.

Figure 5. When users complete a food order, if they are a gold user, award them with A. However, if they are a silver user, award them with B.
Figure 6. When users complete a food or mart order, increment a counter. When the counter reaches 5, send them a message. Once the counter reaches 10, award them with points.
Figure 7. When a user confirms a ride booking, wait for 1 minute, and then conduct A/B testing by sending a message 50% of the time.

The campaign setup in the new UI can be naturally stored as a node tree structure. The following is how the example in figure 5 would look like in JSON format. We assign each node a unique number ID, and store a map of the ID to node content.

{
  "1": {
    "type": "scenario",
    "data": { "eventType": "foodOrderComplete"  },
    "children": ["2", "3"]
  },
  "2": {
    "type": "condition",
    "data": { "lhs": "var.user.tier", "operator": "eq", "rhs": "gold" },
    "children": ["4"]
  },
  "3": {
    "type": "condition",
    "data": { "lhs": "var.user.tier", "operator": "eq", "rhs": "silver" },
    "children": ["5"]
  },
  "4": {
    "type": "action",
    "data": {
      "type": "awardReward",
      "payload": { "rewardID": "ID-of-A"  }
    }
  },
  "5": {
    "type": "action",
    "data": {
      "type": "awardReward",
      "payload": { "rewardID": "ID-of-B"  }
    }
  }
}

Conversion to treatments

The question then arises, how do we execute this node tree as treatments? This requires a conversion process. We then developed the following algorithm for converting the node tree into equivalent treatments:

// convertToTreatments is the main function
func convertToTreatments(rootNode) -> []Treatment:
  output = []

  for each scenario in rootNode.scenarios:
    // traverse down each branch
    context = createConversionContext(scenario)
    for child in rootNode.children:
      treatments = convertHelper(context, child)
      output.append(treatments)

  return output

// convertHelper is a recursive helper function
func convertHelper(context, node) -> []Treatment:
  output = []
  f = getNodeConverterFunc(node.type)
  treatments, updatedContext = f(context, node)

  output.append(treatments)

  for child in rootNode.children:
    treatments = convertHelper(updatedContext, child)
    output.append(treatments)

  return output

The getNodeConverterFunc will return different handler functions according to the node type. Each handler function will either update the conversion context, create treatments, or both.

Table 1. The handler logic mapping for each node type.
Node type Logic
condition Add conditions into the context and return the updated context.
action Return a treatment with the event type, condition from the context, and the action itself.
delay Return a treatment with the event type, condition from the context, and a scheduleDelayedEvent action.
count Return a treatment with the event type, condition from the context, and an incrementUserStats action.
count condition Form a condition with the count key from the context, and return an updated context with the condition.

It is important to note that treatments cannot always be reverted to their original node tree structure. This is because different node trees might be converted into the same set of treatments.

The following is an example where two different node trees setups correspond to the same set of treatments:

  • Food order complete -> if gold user -> then award A
  • Food order complete -> if silver user -> then award B
Figure 8. An example of two node tree setups corresponding to the the same set of treatments.

Therefore, we need to store both the campaign node tree JSON and treatments, along with the mapping between the nodes and the treatments. Campaigns are executed using treatments, but displayed using the node tree JSON.

Figure 9. For each campaign, we store both the node tree JSON and treatments, along with their mapping.

How we handle campaign updates

There are instances where a marketing user updates a campaign after its creation. For such cases we need to identify:

  • Which existing treatments should be removed.
  • Which existing treatments should be updated.
  • What new treatments should be added.

We can do this by using the node-treatment mapping information we stored. The following is the pseudocode for this process:

func howToUpdateTreatments(oldTreatments []Treatment, newTreatments []Treatment):
  treatmentsUpdate = map[int]Treatment // treatment ID -> updated treatment
  treatmentsRemove = []int // list of treatment IDs
  treatmentsAdd = []Treatment // list of new treatments to be created

  matchedOldTreamentIDs = set()

  for newTreatment in newTreatments:
    matched = false

    // see whether the nodes match any old treatment
    for oldTreatment in oldTreatments:
      // two treatments are considered matched if their linked node IDs are identical
      if isSame(oldTreatment.nodeIDs, newTreatment.nodeIDs):
        matched = true
        treatmentsUpdate[oldTreament.ID] = newTreatment
        matchedOldTreamentIDs.Add(oldTreatment.ID)
        break

    // if no match, that means it is a new treatment we need to create
    if not matched:
      treatmentsAdd.Append(newTreatment)

  // all the non-matched old treatments should be deleted
  for oldTreatment in oldTreatments:
    if not matchedOldTreamentIDs.contains(oldTreatment.ID):
      treatmentsRemove.Append(oldTreatment.ID)

  return treatmentsAdd, treatmentsUpdate, treatmentsRemove

For a visual illustration, let’s consider a campaign that initially resembles the one shown in figure 10. The node IDs are highlighted in red.

Figure 10. A campaign in node tree structure.

This campaign will generate two treatments.

Table 2. The campaign shown in the figure 10 will generated two treatments.
ID Treatment Linked node IDs
1 Event: food order complete
Condition: gold user
Action: award A
1, 2, 3
2 Event: food order complete
Condition: silver user
Action: award B
1, 4, 5

After creation, the campaign creator updates the upper condition branch, deletes the lower branch, and creates a new branch. Note that after node deletion, the deleted node ID will not be reused.

Figure 11. An updated campaign in node tree structure.

According to our logic in figure 11, the following update will be performed:

  • Update action for treatment 1 to “award C”.
  • Delete treatment 2
  • Create a new treatment: food -> is promo used -> send push

Conclusion

This article reveals the workings of Trident, our bespoke marketing campaign platform. By exploring the core concept of a “treatment” and additional features like Counter, Delay and Limit, we illustrated the flexibility and sophistication of our system.

We’ve explained changes to the Trident UI that have made campaign creation more intuitive. Transforming campaign setups into executable treatments while preserving the visual representation ensures seamless campaign execution and adaptation.

Our devotion to improving Trident aims to empower our marketing team to design engaging and dynamic campaigns, ultimately providing excellent experiences to our users.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!