Tag Archives: generative AI

Amazon Titan Image Generator v2 is now available in Amazon Bedrock

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/amazon-titan-image-generator-v2-is-now-available-in-amazon-bedrock/

Today, we are announcing the general availability of the Amazon Titan Image Generator v2 model with new capabilities in Amazon Bedrock. With Amazon Titan Image Generator v2, you can guide image creation using reference images, edit existing visuals, remove backgrounds, generate image variations, and securely customize the model to maintain brand style and subject consistency. This powerful tool streamlines workflows, boosts productivity, and brings creative visions to life.

Amazon Titan Image Generator v2 brings a number of new features in addition to all features of Amazon Titan Image Generator v1, including:

  • Image conditioning – Provide a reference image along with a text prompt, resulting in outputs that follow the layout and structure of the user-supplied reference.
  • Image guidance with color palette – Control precisely the color palette of generated images by providing a list of hex codes along with the text prompt.
  • Background removal – Automatically remove background from images containing multiple objects.
  • Subject consistency – Fine-tune the model to preserve a specific subject (for example, a particular dog, shoe, or handbag) in the generated images.

New features in Amazon Titan Image Generator v2
Before getting started, if you are new to using Amazon Titan models, go to the Amazon Bedrock console and choose Model access on the bottom left pane. To access the latest Amazon Titan models from Amazon, request access separately for Amazon Titan Image Generator G1 v2.

Here are details of the Amazon Titan Image Generator v2 in Amazon Bedrock:

Image conditioning
You can use the image conditioning feature to shape your creations with precision and intention. By providing a reference image (that is, a conditioning image), you can instruct the model to focus on specific visual characteristics, such as edges, object outlines, and structural elements, or segmentation maps that define distinct regions and objects within the reference image.

We support two types of image conditioning: Canny edge and segmentation.

  • The Canny edge algorithm is used to extract the prominent edges within the reference image, creating a map that the Amazon Titan Image Generator can then use to guide the generation process. You can “draw” the foundations of your desired image, and the model will then fill in the details, textures, and final aesthetic based on your guidance.
  • Segmentation provides an even more granular level of control. By supplying the reference image, you can define specific areas or objects within the image and instruct the Amazon Titan Image Generator to generate content that aligns with those defined regions. You can precisely control the placement and rendering of characters, objects, and other key elements.

Here are generation examples that use image conditioning.

To use the image conditioning feature, you can use Amazon Bedrock API, AWS SDK, or AWS Command Line Interface (AWS CLI) and choose CANNY_EDGE or SEGMENTATION for controlMode of textToImageParams with your reference image.

	"taskType": "TEXT_IMAGE",
	"textToImageParams": {
 		"text": "a cartoon deer in a fairy world.",
        "conditionImage": input_image, # Optional
        "controlMode": "CANNY_EDGE" # Optional: CANNY_EDGE | SEGMENTATION
        "controlStrength": 0.7 # Optional: weight given to the condition image. Default: 0.7
     }

The following a Python code example using AWS SDK for Python (Boto3) shows how to invoke Amazon Titan Image Generator v2 on Amazon Bedrock to use image conditioning.

import base64
import io
import json
import logging
import boto3
from PIL import Image
from botocore.exceptions import ClientError

def main():
    """
    Entrypoint for Amazon Titan Image Generator V2 example.
    """
    try:
        logging.basicConfig(level=logging.INFO,
                            format="%(levelname)s: %(message)s")

        model_id = 'amazon.titan-image-generator-v2:0'

        # Read image from file and encode it as base64 string.
        with open("/path/to/image", "rb") as image_file:
            input_image = base64.b64encode(image_file.read()).decode('utf8')

        body = json.dumps({
            "taskType": "TEXT_IMAGE",
            "textToImageParams": {
                "text": "a cartoon deer in a fairy world",
                "conditionImage": input_image,
                "controlMode": "CANNY_EDGE",
                "controlStrength": 0.7
            },
            "imageGenerationConfig": {
                "numberOfImages": 1,
                "height": 512,
                "width": 512,
                "cfgScale": 8.0
            }
        })

        image_bytes = generate_image(model_id=model_id,
                                     body=body)
        image = Image.open(io.BytesIO(image_bytes))
        image.show()

    except ClientError as err:
        message = err.response["Error"]["Message"]
        logger.error("A client error occurred: %s", message)
        print("A client error occured: " +
              format(message))
    except ImageError as err:
        logger.error(err.message)
        print(err.message)

    else:
        print(
            f"Finished generating image with Amazon Titan Image Generator V2 model {model_id}.")

def generate_image(model_id, body):
    """
    Generate an image using Amazon Titan Image Generator V2 model on demand.
    Args:
        model_id (str): The model ID to use.
        body (str) : The request body to use.
    Returns:
        image_bytes (bytes): The image generated by the model.
    """

    logger.info(
        "Generating image with Amazon Titan Image Generator V2 model %s", model_id)

    bedrock = boto3.client(service_name='bedrock-runtime')

    accept = "application/json"
    content_type = "application/json"

    response = bedrock.invoke_model(
        body=body, modelId=model_id, accept=accept, contentType=content_type
    )
    response_body = json.loads(response.get("body").read())

    base64_image = response_body.get("images")[0]
    base64_bytes = base64_image.encode('ascii')
    image_bytes = base64.b64decode(base64_bytes)

    finish_reason = response_body.get("error")

    if finish_reason is not None:
        raise ImageError(f"Image generation error. Error is {finish_reason}")

    logger.info(
        "Successfully generated image with Amazon Titan Image Generator V2 model %s", model_id)

    return image_bytes
	
class ImageError(Exception):
    "Custom exception for errors returned by Amazon Titan Image Generator V2"

    def __init__(self, message):
        self.message = message

logger = logging.getLogger(__name__)
logging.basicConfig(level=logging.INFO)

if __name__ == "__main__":
    main()

Color conditioning
Most designers want to generate images adhering to color branding guidelines so they seek control over color palette in the generated images.

With the Amazon Titan Image Generator v2, you can generate color-conditioned images based on a color palette—a list of hex colors provided as part of the inputs adhering to color branding guidelines. You can also provide a reference image as input (optional) to generate an image with provided hex colors while inheriting style from the reference image.

In this example, the prompt describes:
a jar of salad dressing in a rustic kitchen surrounded by fresh vegetables with studio lighting

The generated image reflects both the content of the text prompt and the specified color scheme to align with the brand’s color guidelines.

To use color conditioning feature, you can set taskType to COLOR_GUIDED_GENERATION with your prompt and hex codes.

       "taskType": "COLOR_GUIDED_GENERATION",
       "colorGuidedGenerationParam": {
             "text": "a jar of salad dressing in a rustic kitchen surrounded by fresh vegetables with studio lighting",                         
	         "colors": ['#ff8080', '#ffb280', '#ffe680', '#e5ff80'], # Optional: list of color hex codes 
             "referenceImage": input_image, #Optional
        }

Background removal
Whether you’re looking to composite an image onto a solid color backdrop or layer it over another scene, the ability to cleanly and accurately remove the background is an essential tool in the creative workflow. You can instantly remove the background from your images with a single step. Amazon Titan Image Generator v2 can intelligently detect and segment multiple foreground objects, ensuring that even complex scenes with overlapping elements are cleanly isolated.

The example shows an image of an iguana sitting on a tree in a forest. The model was able to identify the iguana as the main object and remove the forest background, replacing it with a transparent background. This lets the iguana stand out clearly without the distracting forest around it.

To use background removal feature, you can set taskType to BACKGROUND_REMOVAL with your input image.

    "taskType": "BACKGROUND_REMOVAL",
    "backgroundRemovalParams": {
 		"image": input_image,
    }

Subject consistency with fine-tuning
You can now seamlessly incorporate specific subjects into visually captivating scenes. Whether it’s a brand’s product, a company logo, or a beloved family pet, you can fine-tune the Amazon Titan model using reference images to learn the unique characteristics of the chosen subject.

Once the model is fine-tuned, you can simply provide a text prompt, and the Amazon Titan Generator will generate images that maintain a consistent depiction of the subject, placing it naturally within diverse, imaginative contexts. This opens up a world of possibilities for marketing, advertising, and visual storytelling.

For example, you could use an image with the caption Ron the dog during fine-tuning, give the prompt as Ron the dog wearing a superhero cape during inference with the fine-tuned model, and get a unique image in response.

To learn, visit model inference parameters and code examples for Amazon Titan Image Generator in the AWS documentation.

Now available
The Amazon Titan Generator v2 model is available today in Amazon Bedrock in the US East (N. Virginia) and US West (Oregon) Regions. Check the full Region list for future updates. To learn more, check out the Amazon Titan product page and the Amazon Bedrock pricing page.

Give Amazon Titan Image Generator v2 a try in Amazon Bedrock today, and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

Visit our community.aws site to find deep-dive technical content and to discover how our Builder communities are using Amazon Bedrock in their solutions.

— Channy
How we improved translation experience with cost efficiency

Post Syndicated from Grab Tech original https://engineering.grab.com/improved-translation-experience-with-cost-efficiency

Introduction

As COVID restrictions were fully lifted in 2023, the number of tourists grew dramatically. People began to explore the world again, frequently using the Grab app to make bookings outside of their home country. However, we noticed that communication posed a challenge for some users. Despite our efforts to integrate an auto-translation feature in the booking chat, we received feedback about occasional missed or inaccurate translations. You can refer to this blog for a better understanding of Grab’s chat system.

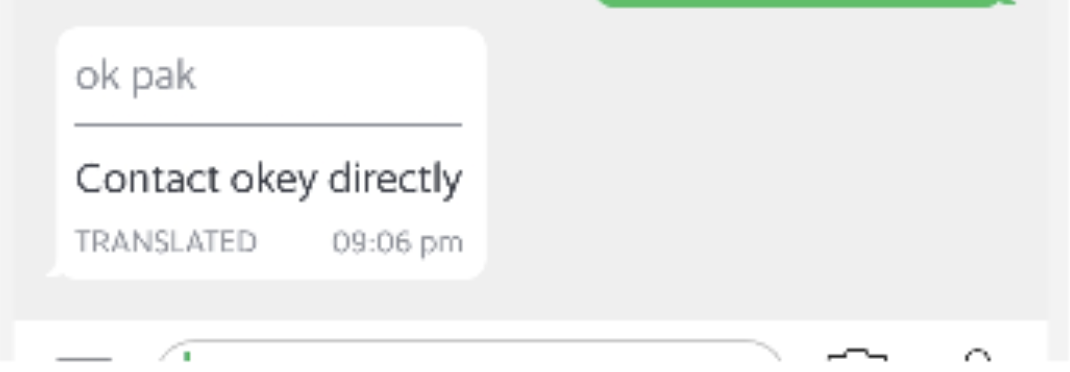
An example of a bad translation. The correct translation is: ‘ok sir’.

In an effort to enhance the user experience for travellers using the Grab app, we formed an engineering squad to tackle this problem. The objectives are as follows:

  • Ensure translation is provided when it’s needed.
  • Improve the quality of translation.
  • Maintain the cost of this service within a reasonable range.

Ensure translation is provided when it’s needed

Originally, we relied on users’ device language settings to determine if translation is needed. For example, if both the passenger and driver’s language setting is set to English, translation is not needed. Interestingly, it turned out that the device language setting did not reliably indicate the language in which a user would send their messages. There were numerous cases where despite having their device language set to English, drivers sent messages in another language.

Therefore, we needed to detect the language of user messages on the fly to make sure we trigger translation when it’s needed.

Language detection

Simple as it may seem, language detection is not that straightforward a task. We were unable to find an open-source language detector library that covered all Southeast Asian languages. We looked for Golang libraries as our service was written in Golang. The closest we could find were the following:

  • Whatlang: unable to detect Malay
  • Lingua: unable to detect Burmese and Khmer

We decided to choose Lingua over Whatlang as the base detector due to the following factors:

  • Overall higher accuracy.
  • Capability to provide detection confidence level.
  • We have more users using Malay than those using Burmese or Khmer.

When a translation request comes in, our first step is to use Lingua for language detection. If the detection confidence level falls below a predefined threshold, we fall back to call the third-party translation service as it can detect all Southeast Asian languages.

You may ask, why don’t we simply use the third-party service in the first place. It’s because:

  • The third-party service only has a translate API that also does language detection, but it does not provide a standalone language detection API.
  • Using the translate API is costly, so we need to avoid calling it when it’s unnecessary. We will cover more on this in a later section.

Another challenge we’ve encountered is the difficulty of distinguishing between Malay and Indonesian languages due to their strong similarities and shared vocabulary. The identical text might convey different meanings in these two languages, which the third-party translation service struggles to accurately detect and translate.

Differentiating Malay and Indonesian is a tough problem in general. However, in our case, the detection has a very specific context, and we can make use of the context to enhance our detection accuracy.

Making use of translation context

All our translations are for the messages sent in the context of a booking or order, predominantly between passenger and driver. There are two simple facts that can aid in our language detection:

  • Booking/order happens in one single country.
  • Drivers are almost always local to that country.

So, for a booking that happens in an Indonesian city, if the driver’s message is detected as Malay, it’s highly likely that the message is actually in Bahasa Indonesia.

Improve quality of translation

Initially, we were entirely dependent on a third-party service for translating our chat messages. While overall powerful, the third-party service is not perfect, and it does generate weird translations from time to time.

An example of a weird translation from a third-party service recorded on 19 Dec 2023.

Then, it came to us that we might be able to build an in-house translation model that could translate chat messages better than the third-party service. The reasons being:

  • The scope of our chat content is highly specific. All the chats are related to bookings or orders. There would not be conversations about life or work in the chat. Maybe a small Machine Learning (ML) model would suffice to do the job.
  • The third-party service is a general translation service. It doesn’t know the context of our messages. We, however, know the whole context. Having the right context gives us a great edge on generating the right translation.

Training steps

To create our own translation model, we took the following steps:

  • Perform topic modelling on Grab chat conversations.
  • Worked with the localisation team to create a benchmark set of translations.
  • Measured existing translation solutions against benchmarks.
  • Used an open source Large Language Model (LLM) to produce synthetic training data.
  • Used synthetic data to train our lightweight translation model.

Topic modelling

In this step, our aim was to generate a dataset which is both representative of the chat messages sent by our users and diverse enough to capture all of the nuances of the conversations. To achieve this, we took a stratified sampling approach. This involved a random sample of past chat conversation messages stratified by various topics to ensure a comprehensive and balanced representation.

Developing a benchmark

For this step we engaged Grab’s localisation team to create a benchmark for translations. The intention behind this step wasn’t to create enough translation examples to fully train or even finetune a model, but rather, it was to act as a benchmark for translation quality, and also as a set of few-shot learning examples for when we generate our synthetic data.

This second point was critical! Although LLMs can generate good quality translations, LLMs are highly susceptible to their training examples. Thus, by using a set of handcrafted translation examples, we hoped to produce a set of examples that would teach the model the exact style, level of formality, and correct tone for the context in which we plan to deploy the final model.

Benchmarking

From a theoretical perspective there are two ways that one can measure the performance of a machine translation system. The first is through the computation of some sort of translation quality score such as a BLEU or CHRF++ score. The second method is via subjective evaluation. For example, you could give each translation a score from 1 to 5 or pit two translations against each other and ask someone to assess which they prefer.

Both methods have their relative strengths and weaknesses. The advantage of a subjective method is that it corresponds better with what we want, a high quality translation experience for our users. The disadvantage of this method is that it is quite laborious. The opposite is true for the computed translation quality scores, that is to say that they correspond less well to a human’s subjective experience of our translation quality, but that they are easier and faster to compute.

To overcome the inherent limitations of each method, we decided to do the following:

  1. Set a benchmark score for the translation quality of various translation services using a CHRF++ score.
  2. Train our model until its CHRF++ score is significantly better than the benchmark score.
  3. Perform a manual A/B test between the newly trained model and the existing translation service.

Synthetic data generation

To generate the training data needed to create our model, we had to rely on an open source LLM to generate the synthetic translation data. For this task, we spent considerable effort looking for a model which had both a large enough parameter count to ensure high quality outputs, but also a model which had the correct tokenizer to handle the diverse sets of languages which Grab’s customers speak. This is particularly important for languages which use non-standard character sets such as Vietnamese and Thai. We settled on using a public model from Hugging Face for this task.

We then used a subset of the previously mentioned benchmark translations to input as few-shot learning examples to our prompt. After many rounds of iteration, we were able to generate translations which were superior to the benchmark CHRF++ scores which we had attained in the previous section.

Model fine tuning

We now had one last step before we had something that was production ready! Although we had successfully engineered a prompt capable of generating high quality translations from the public Hugging Face model, there was no way we’d be able to deploy such a model. The model was far too big for us to deploy it in a cost efficient manner and within an acceptable latency. Our solution to this was to fine-tune a smaller bespoke model using the synthetic training data which was derived from the larger model.

These models were language specific (e.g. English to Indonesian) and built solely for the purpose of language translation. They are 99% smaller than the public model. With approximately 10 Million synthetic training examples, we were able to achieve performance which was 98% as effective as our larger model.

We deployed our model and ran several A/B tests with it. Our model performed pretty well overall, but we noticed a critical problem: sometimes, numbers got mutated in the translation. These numbers can be part of an address, phone number, price etc. Showing the wrong number in a translation can cause great confusion to the users. Unfortunately, an ML model’s output can never be fully controlled; therefore, we added an additional layer of programmatic check to mitigate this issue.

Post-translation quality check

Our goal is to ensure non-translatable content such as numbers, special symbols, and emojis in the original message doesn’t get mutated in the translation produced by our in-house model. We extract all the non-translatable content from the original message, count the occurrences of each, and then try to match the same in the translation. If it fails to match, we discard the in-house translation and fall back to using the third-party translation service.

Keep cost low

At Grab, we try to be as cost efficient as possible in all aspects. In the case of translation, we tried to minimise cost by avoiding unnecessary on-the-fly translations.

As you would have guessed, the first thing we did was to implement caching. A cache layer is placed before both the in-house translation model and the third-party translation. We try to serve translation from the cache first before hitting the underlying translation service. However, given that translation requests are in free text and can be quite dynamic, the impact of caching is limited. There’s more we need to do.

For context, in a booking chat, other than the users, Grab’s internal services can also send messages to the chat room. These messages are called system messages. For example,our food service always sends a message with information on the food order when an order is confirmed.

System messages are all fairly static in nature, however, we saw a very high amount of translation cost attributed to system messages. Taking a deeper look, we noticed the following:

  • Many system messages were not sent in the recipient’s language, thus requiring on-the-fly translation.
  • Many system messages, though having the same static structure, contain quite a few variants such as passenger’s name and food order item name. This makes it challenging to utilise our translation cache effectively as each message is different.

Since all system messages are manually prepared, we should be able to get them all manually translated into all the required languages, and avoid on-the-fly translations altogether.

Therefore, we launched an internal campaign, mandating all internal services that send system messages to chat rooms to get manual translations prepared, and pass in the translated contents. This alone helped us save roughly US$255K a year!

Next steps

At Grab, we firmly believe that our proprietary in-house translation models are not only more cost-effective but cater more accurately to our unique use cases compared to third-party services. We will focus on expanding these models to more languages and countries across our operating regions.

Additionally, we are exploring opportunities to apply learnings of our chat translations to other Grab content. This strategy aims to guarantee a seamless language experience for our rapidly expanding user base, especially travellers. We are enthusiastically looking forward to the opportunities this journey brings!

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 428 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Testing your applications with Amazon Q Developer

Post Syndicated from Svenja Raether original https://aws.amazon.com/blogs/devops/testing-your-applications-with-amazon-q-developer/

Testing code is a fundamental step in the field of software development. It ensures that applications are reliable, meet quality standards, and work as intended. Automated software tests help to detect issues and defects early, reducing impact to end-user experience and business. In addition, tests provide documentation and prevent regression as code changes over time.

In this blog post, we show how the integration of generative AI tools like Amazon Q Developer can further enhance unit testing by automating test scenarios and generating test cases.

Amazon Q Developer helps developers and IT professionals with all of their tasks across the software development lifecycle – from coding, testing, and upgrading, to troubleshooting, performing security scanning and fixes, optimizing AWS resources, and creating data engineering pipelines. It integrates into your Integrated Development Environment (IDE) and aids with providing answers to your questions. Amazon Q Developer supports you across the Software Development Lifecycle (SLDC) by enriching feature and test development with step-by-step instructions and best practices. It learns from your interactions and training itself over time to output personalized, and tailored answers.

Solution overview

In this blog, we show how to use Amazon Q Developer to:

  • learn about software testing concepts and frameworks
  • identify unit test scenarios
  • write unit test cases
  • refactor test code
  • mock dependencies
  • generate sample data

Note: Amazon Q Developer may generate an output different from this blog post’s examples due to its nondeterministic nature.

Using Amazon Q Developer to learn about software testing frameworks and concepts

As you start gaining experience with testing, Amazon Q Developer can accelerate your learning through conversational Q&A directly within the AWS Management Console or the IDE. It can explain topics, provide general advice and share helpful resources on testing concepts and frameworks. It gives personalized recommendations on resources which makes the learning experience more interactive and accelerates the time to get started with writing unit tests. Let’s introduce an example conversation to demonstrate how you can leverage Amazon Q Developer for learning before attempting to write your first test case.

Example – Select and install frameworks

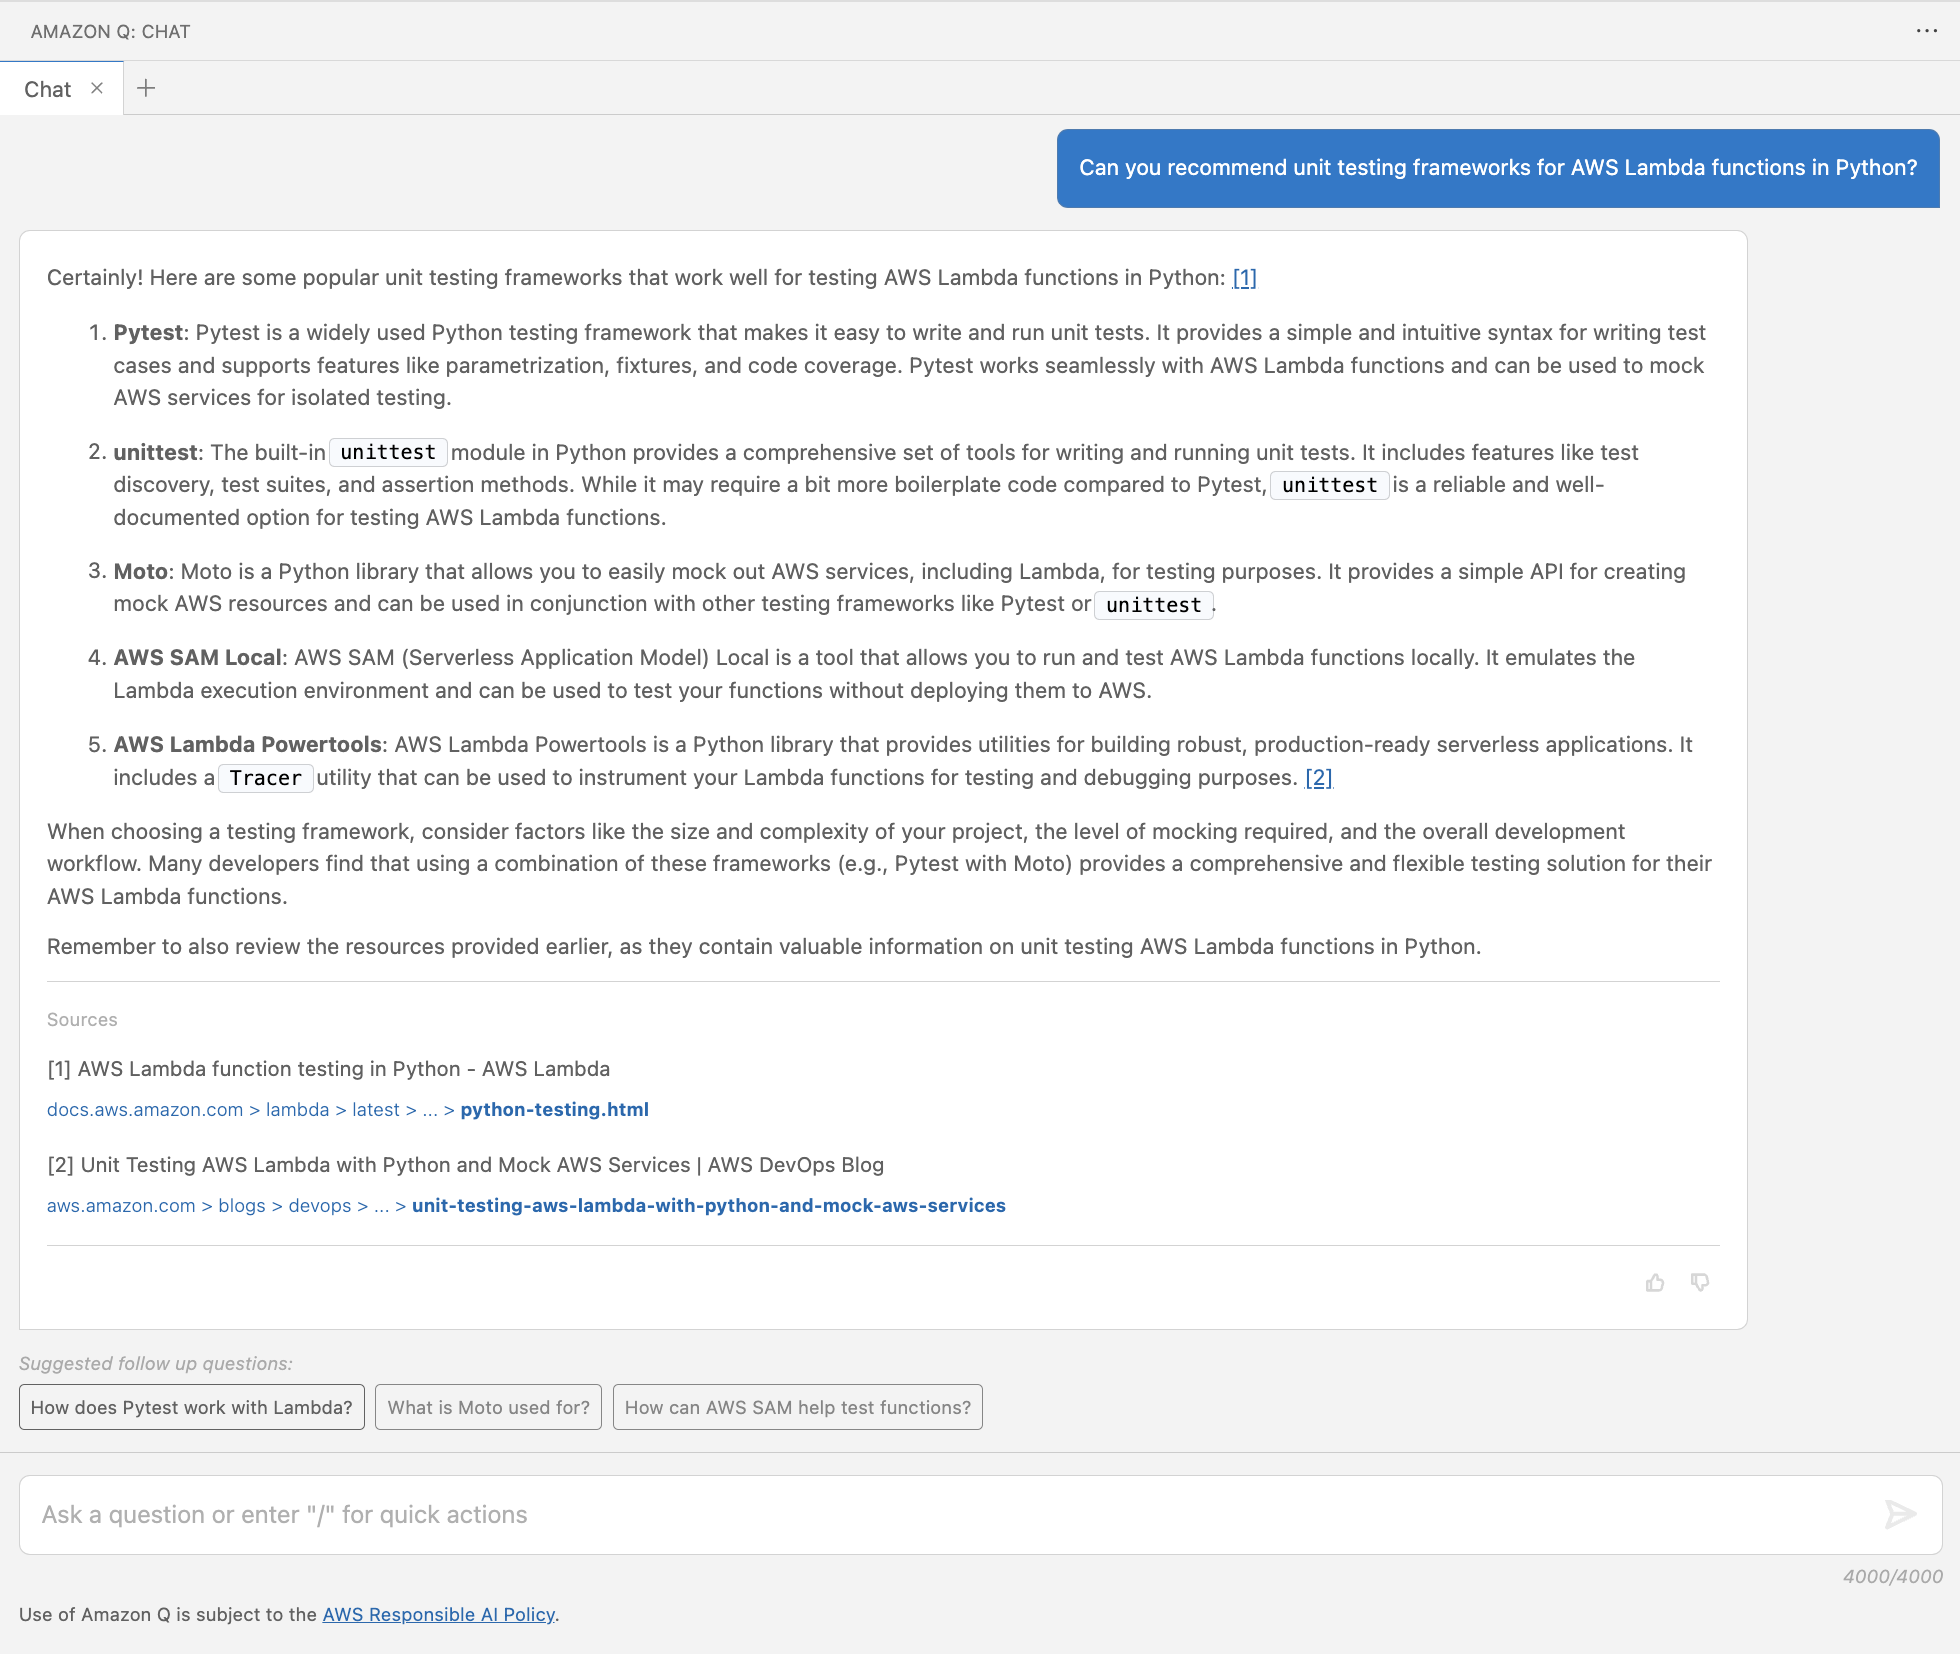
A unit testing framework is a software tool used for test automation, design and management of test cases. Upon starting a software project, you may be faced with the selection of a framework depending on the type of tests, programming language, and underlying technology. Let’s ask for recommendations around unit testing frameworks for Python code running in an AWS Lambda function.

In the Visual Studio Code IDE, a user asks Amazon Q Developer for recommendations on unit test frameworks suitable for AWS Lambda functions written in Python using the following prompt: “Can you recommend unit testing frameworks for AWS Lambda functions in Python?”. Amazon Q Developer returns a numbered list of popular unit testing frameworks, including Pytest, unittest, Moto, AWS SAM Local, and AWS Lambda Powertools. Amazon Q Developer returns two URLs in the Sources section. The first URL links to an article called “AWS Lambda function testing in Python – AWS Lambda” from the AWS documentation, and the other URL to an AWS DevOps Blog post with the title “Unit Testing AWS Lambda with Python and Mock AWS Services”.

Figure 1: Recommend unit testing frameworks for AWS Lambda functions in Python

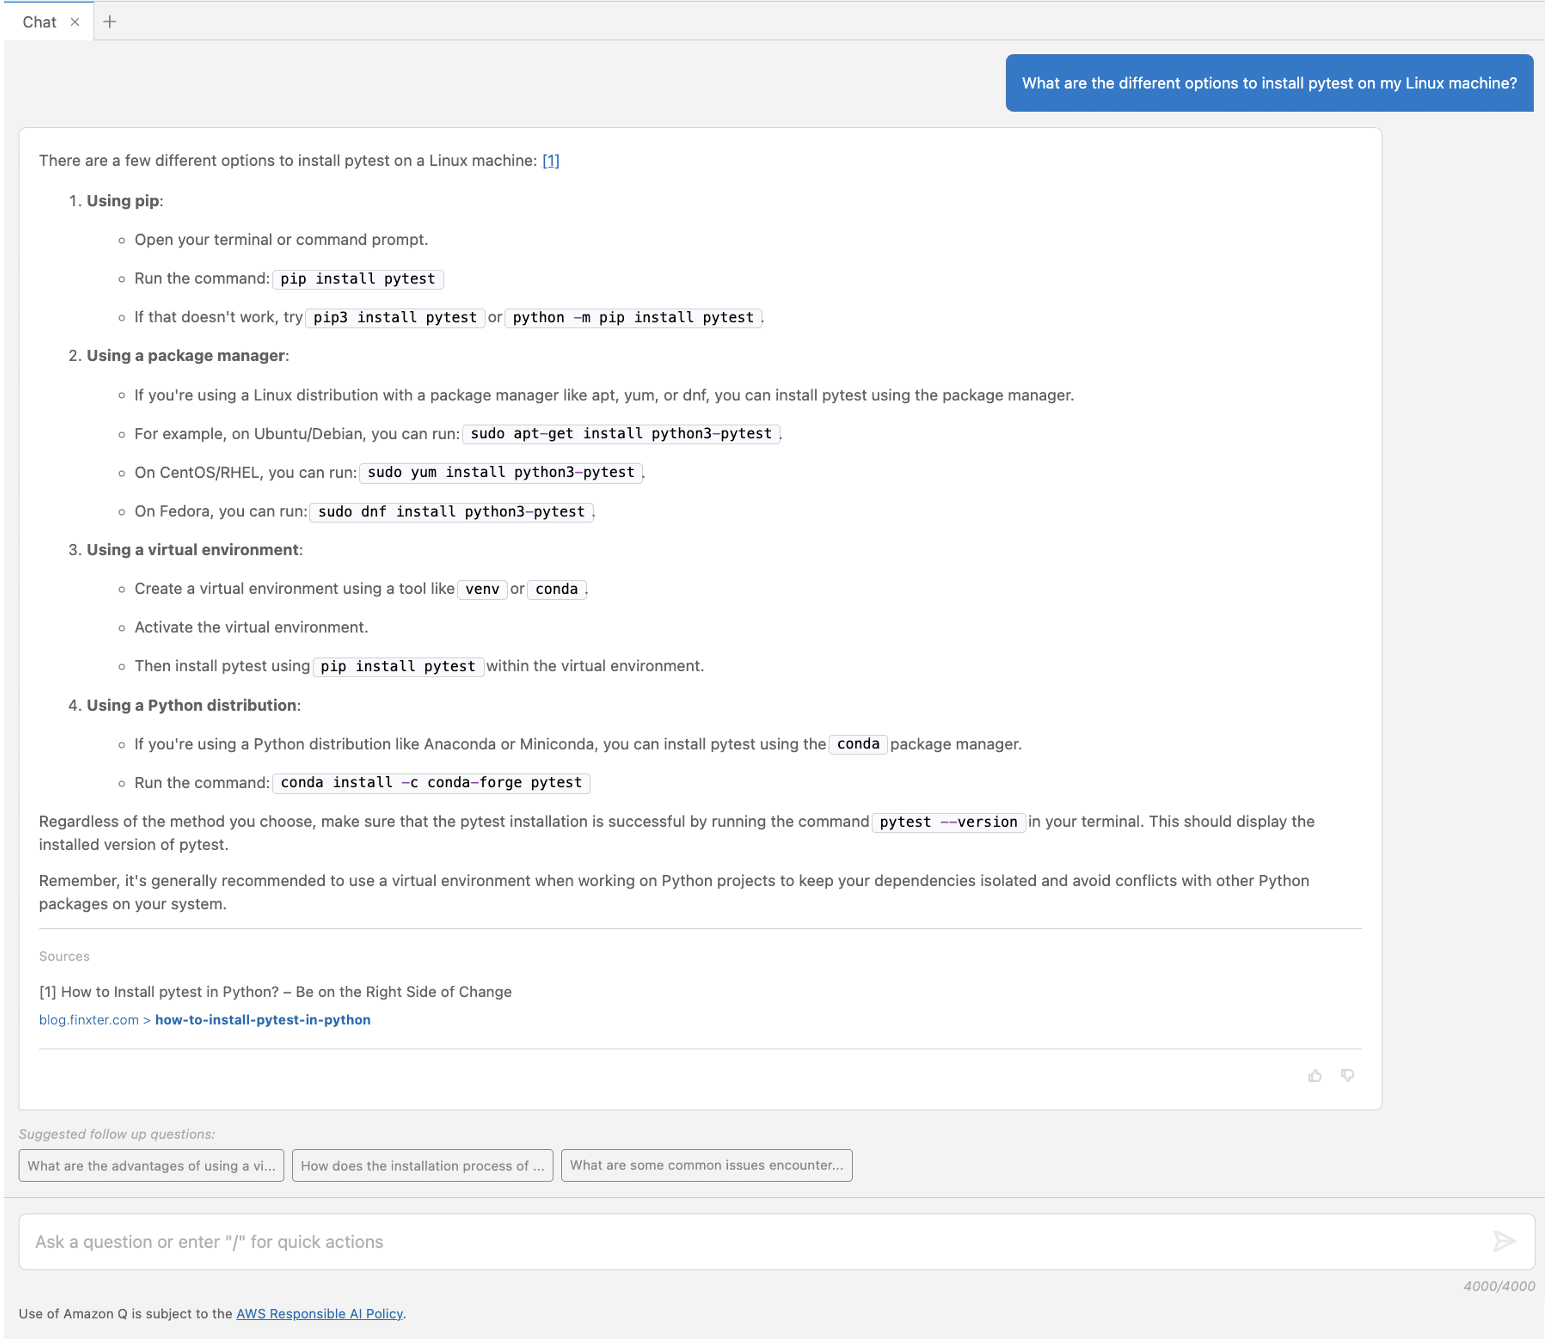
In Figure 1, Amazon Q Developer answers with popular frameworks (pytest, unittest, Moto, AWS SAM Command Line Interface, and Powertools for AWS Lambda) including a brief description for each of them. It provides a reference to the sources of its response at the bottom and suggested follow up questions. As a next step, you may want to refine what you are looking for with a follow-up question. Amazon Q Developer uses the context from your previous questions and answers to give more precise answers as you continue the conversation. For example, one of the frameworks it suggested using was pytest. If you don’t know how to install that locally, you can ask something like “What are the different options to install pytest on my Linux machine?”. As shown in Figure 2, Amazon Q Developer provides installation recommendation using Python.

In the Visual Studio Code IDE, a user asks Amazon Q Developer about the different options to install pytest on a Linux machine using the following prompt: “What are the different options to install pytest on my Linux machine?”. Amazon Q Developer replies with four different options: using pip, using a package manager, using a virtual environment, and using a Python distribution. Each option includes the steps to install pytest. A source URL is included for an article called “How to install pytest in Python? – Be on the Right Side of Change”.

Figure 2: Options to install pytest

Example – Explain concepts

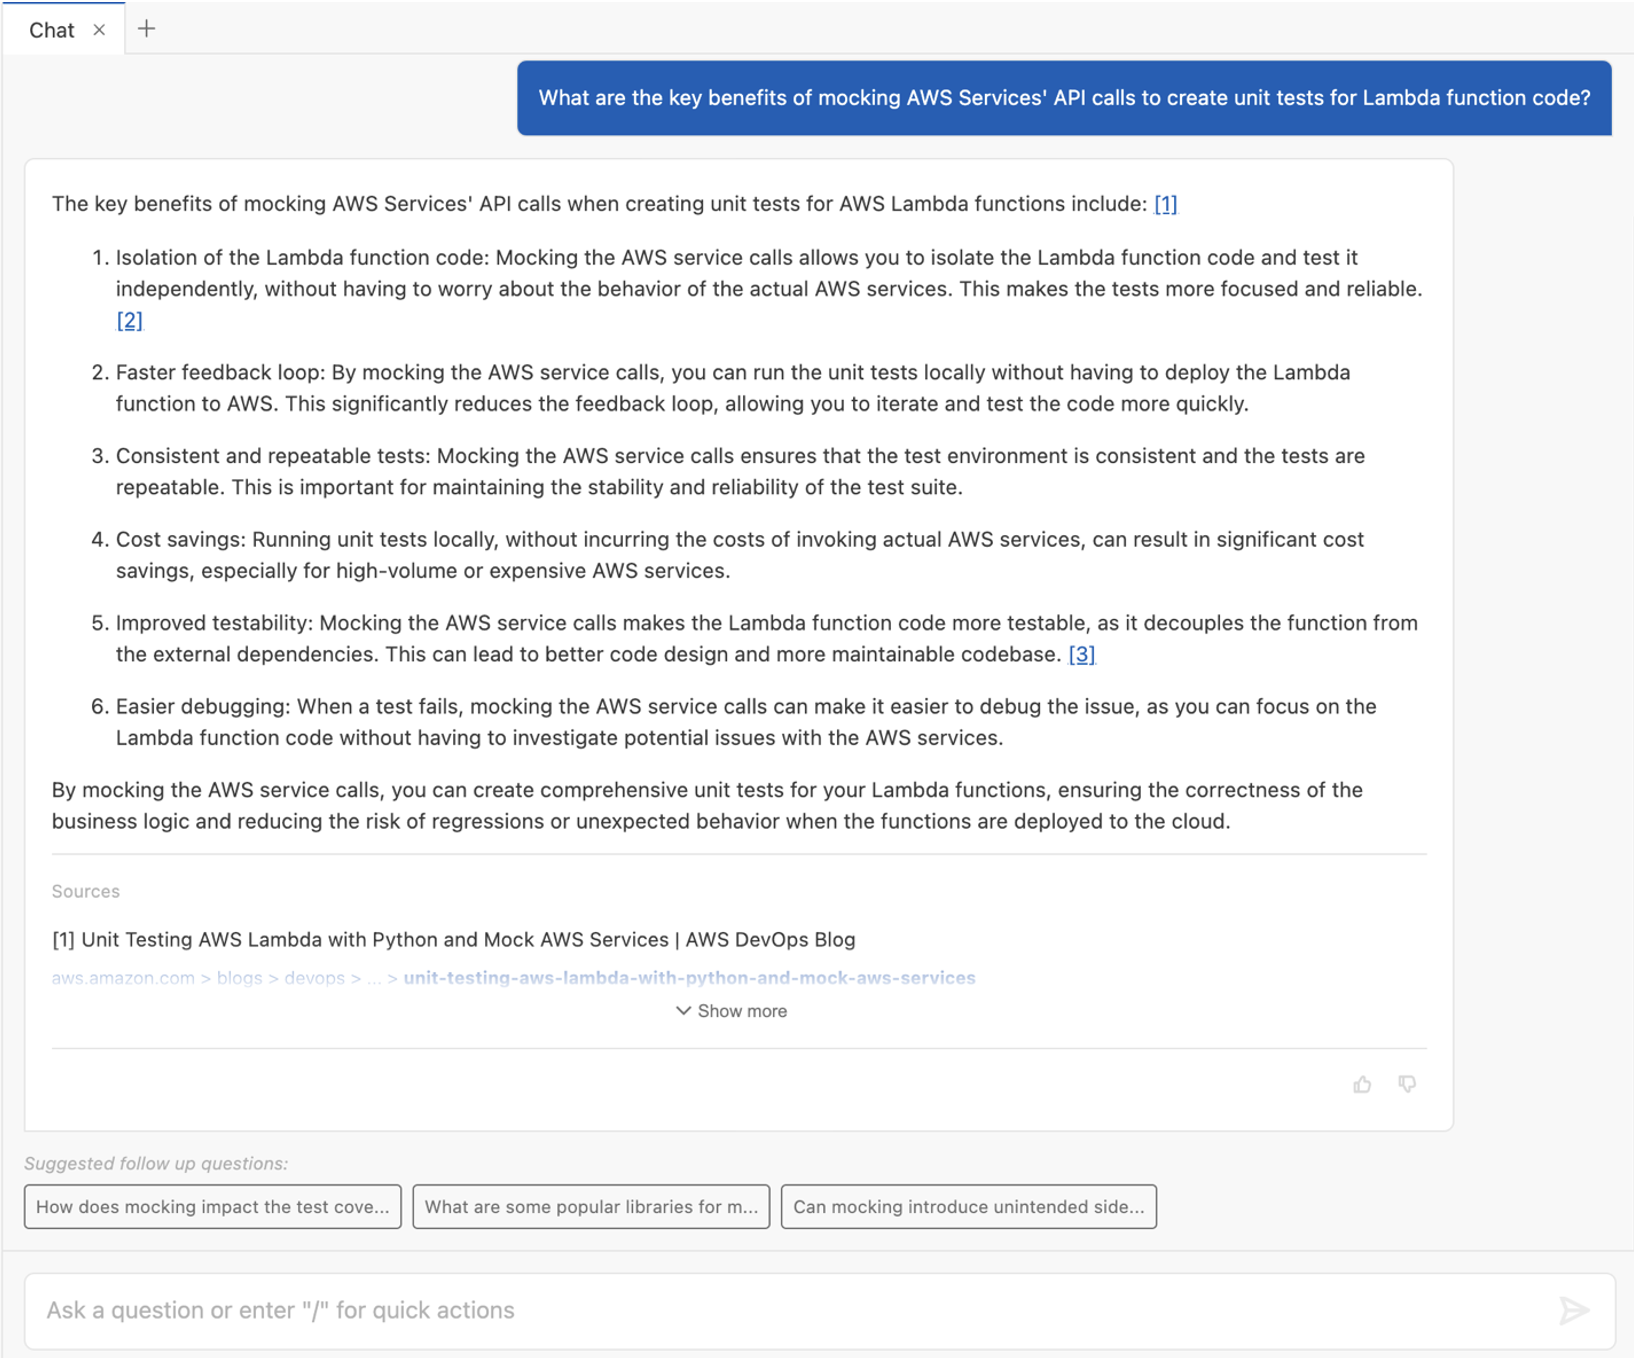
Amazon Q Developer can also help you to get up to speed with testing concepts, such as mocking service dependencies. Let’s ask another follow up question to explain the benefits of mocking AWS services.

In the Visual Studio Code IDE, a user asks Amazon Q Developer about the key benefits of mocking AWS Services’ API calls to create unit tests for Lambda function code using the following prompt: “What are the key benefits of mocking AWS Services' API calls to create unit tests for Lambda function code?”. Amazon Q Developer replies with six key benefits, including: Isolation of the Lambda function code, Faster feedback loop, Consistent and repeatable tests, Cost savings, Improved testability, and Easier debugging. Each benefit has a brief explanation attached to it. The Sources section includes one URL to an AWS DevOps Blog post with the title “Unit Testing AWS Lambda with Python and Mock AWS Services”.

Figure 3: Benefits of mocking AWS services

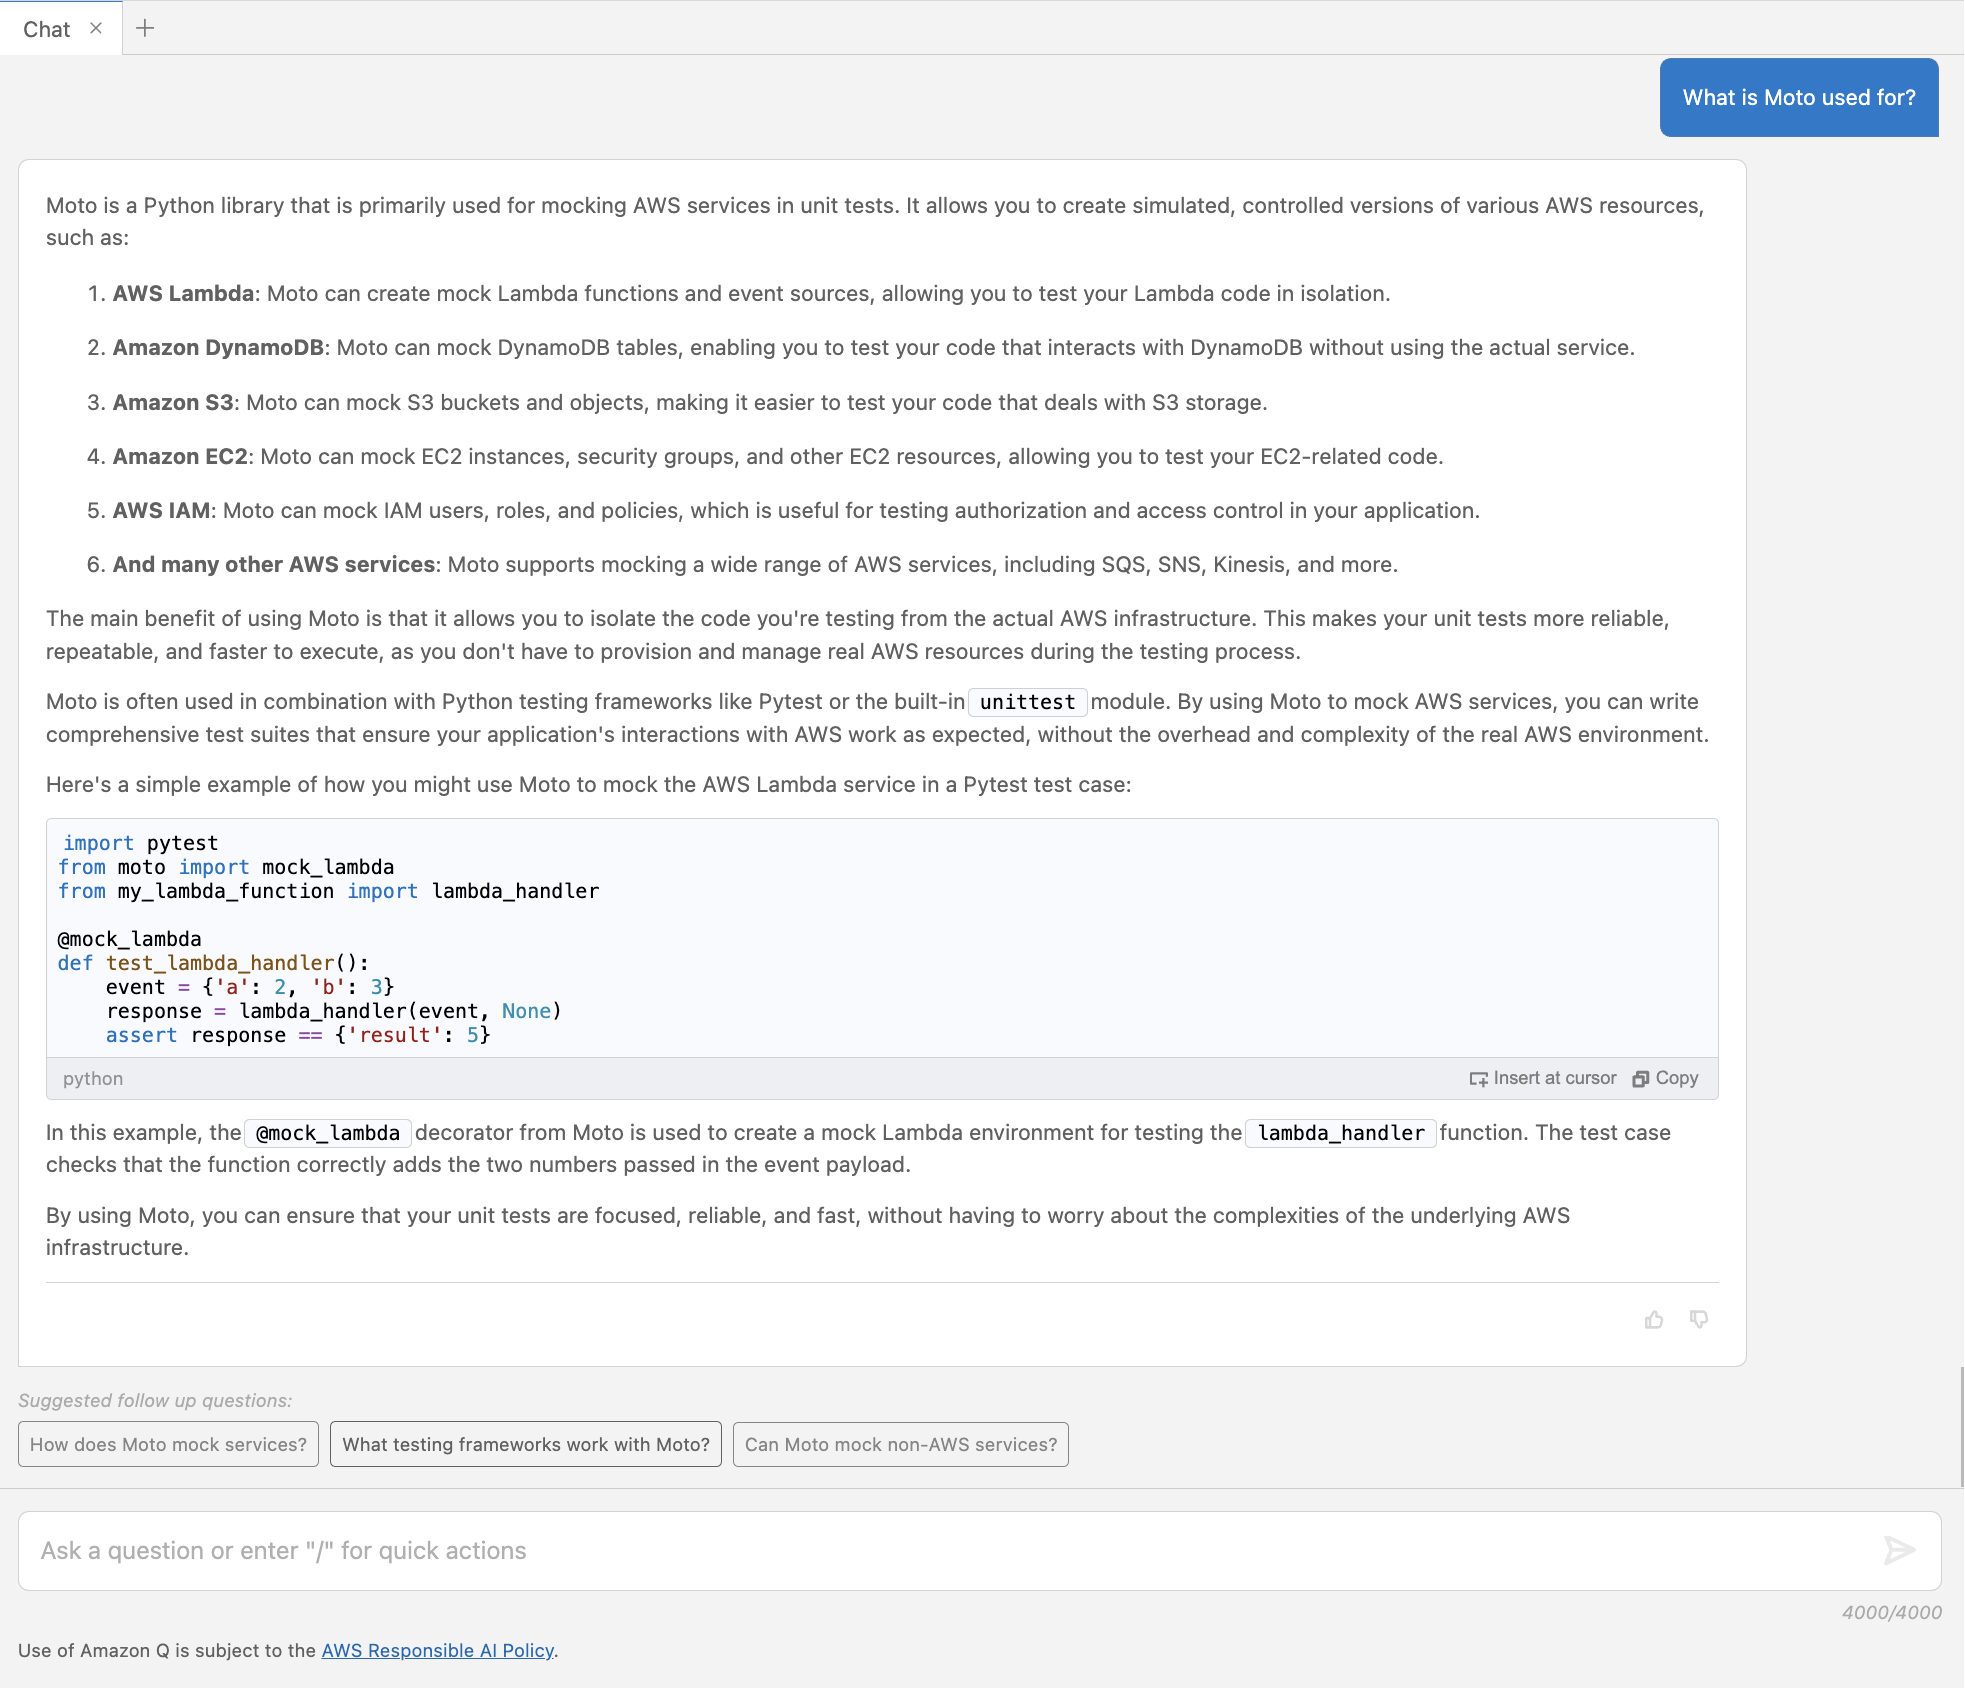
The above conversation in Figure 3 shows how Amazon Q Developer can help to understand concepts. Let’s learn more about Moto.

In the Visual Studio Code IDE, a user asks Amazon Q Developer: “What is Moto used for?”. Amazon Q Developer provides a brief explanation of the Moto library, and how it can be used to create simulations of various AWS resources, such as: AWS Lambda, Amazon Dynamo DB, Amazon S3, Amazon EC2, AWS IAM, and many other AWS services. Amazon Q Developer provides a simple code example of how to use Moto to mock the AWS Lambda service in a Pytest test case by using the @mock_lambda decorator.

Figure 4: Follow up question about Moto

In Figure 4, Amazon Q Developer gives more details about the Moto framework and provides a short example code snippet for mocking an AWS Lambda service.

Best Practice – Write clear prompts

Writing clear prompts helps you to get the desired answers from Amazon Q. A lack of clarity and topic understanding may result in unclear questions and irrelevant or off-target responses. Note how those prompts contain specific description of what the answer should provide. For example, Figure 1 includes the programming language (Python) and service (AWS Lambda) to be considered in the expected answer. If unfamiliar with a topic, leverage Amazon Q Developer as part of your research, to better understand that topic.

Using Amazon Q Developer to identify unit test cases

Understanding the purpose and intended functionality of the code is important for developing relevant test cases. We introduce an example use case in Python, which handles payroll calculation for different hour rates, hours worked, and tax rates.

"""
This module provides a Payroll class to calculate the net pay for an employee.

The Payroll class takes in the hourly rate, hours worked, and tax rate, and
calculates the gross pay, tax amount, and net pay.
"""

class Payroll:
    """
    A class to handle payroll calculations.
    """

    def __init__(self, hourly_rate: float, hours_worked: float, tax_rate: float):
        self._validate_inputs(hourly_rate, hours_worked, tax_rate)
        self.hourly_rate = hourly_rate
        self.hours_worked = hours_worked
        self.tax_rate = tax_rate

    def _validate_inputs(self, hourly_rate: float, hours_worked: float, tax_rate: float) -> None:
        """
        Validate the input values for the Payroll class.

        Args:
            hourly_rate (float): The employee's hourly rate.
            hours_worked (float): The number of hours the employee worked.
            tax_rate (float): The tax rate to be applied to the employee's gross pay.

        Raises:
            ValueError: If the hourly rate, hours worked, or tax rate is not a positive number, 
            or if the tax rate is not between 0 and 1.
        """
        if hourly_rate <= 0:
            raise ValueError("Hourly rate must be a non-negative number.")
        if hours_worked < 0:
            raise ValueError("Hours worked must be a non-negative number.")
        if tax_rate < 0 or tax_rate >= 1:
            raise ValueError("Tax rate must be between 0 and 1.")

    def gross_pay(self) -> float:
        """
        Calculate the employee's gross pay.

        Returns:
            float: The employee's gross pay.
        """
        return self.hourly_rate * self.hours_worked

    def tax_amount(self) -> float:
        """
        Calculate the tax amount to be deducted from the employee's gross pay.

        Returns:
            float: The tax amount.
        """
        return self.gross_pay() * self.tax_rate

    def net_pay(self) -> float:
        """
        Calculate the employee's net pay after deducting taxes.

        Returns:
            float: The employee's net pay.
        """
        return self.gross_pay() - self.tax_amount()

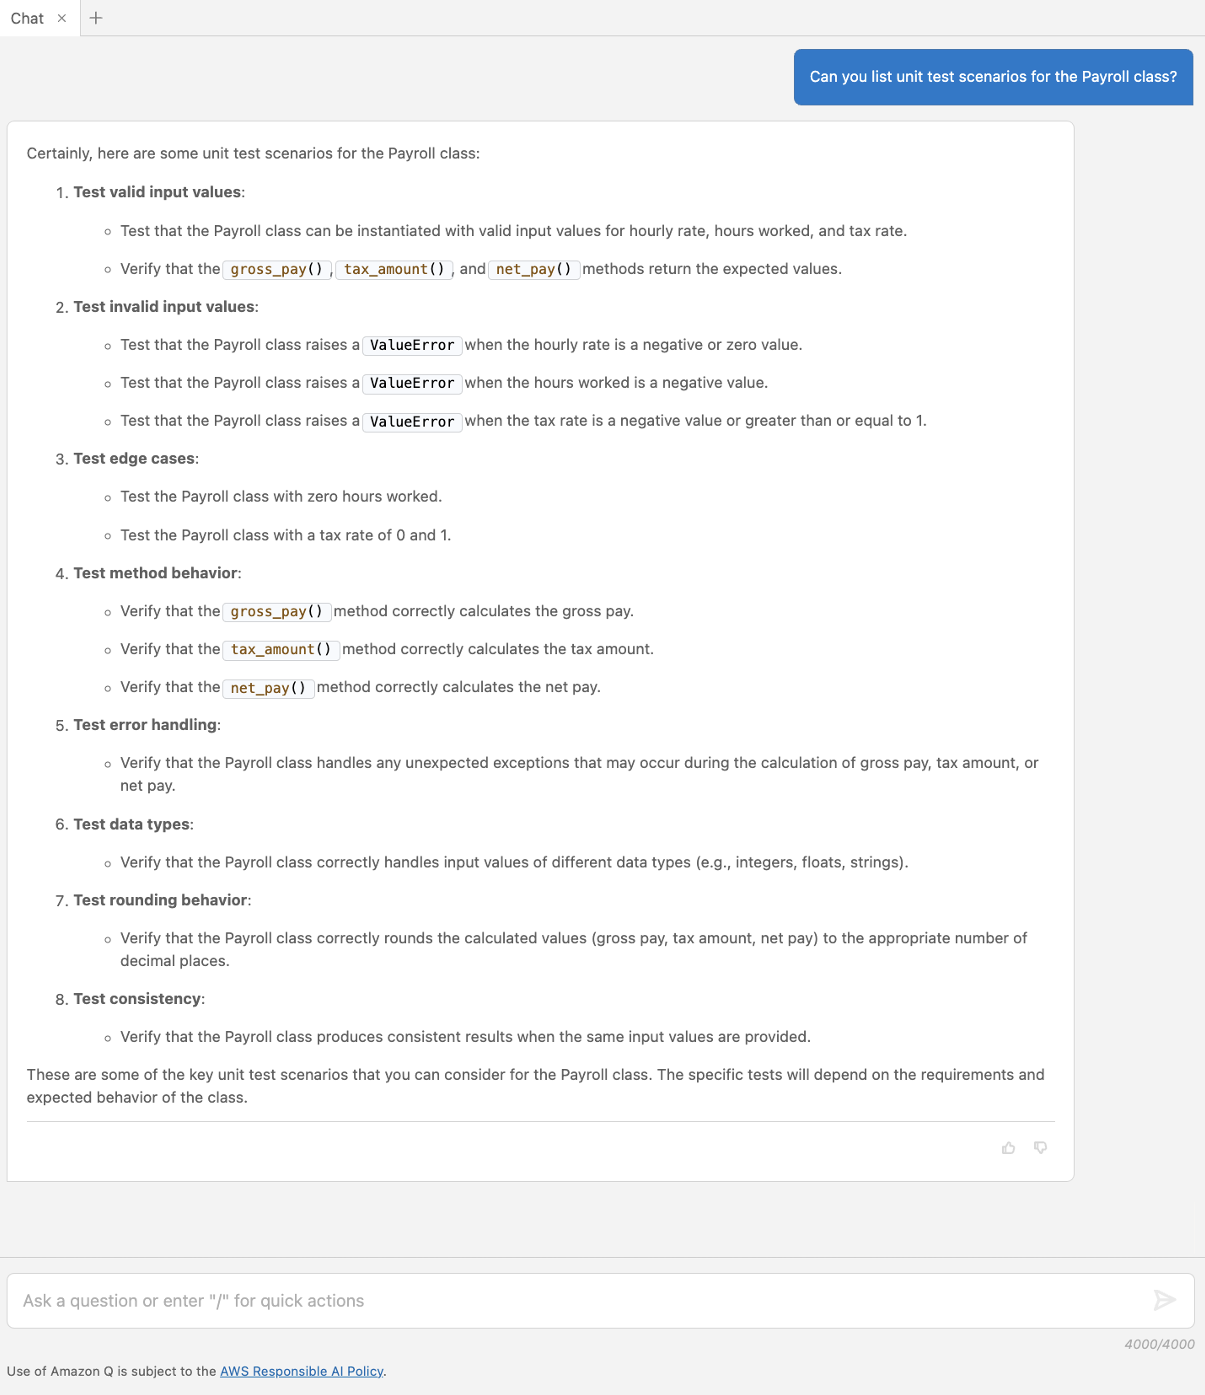
The example shows how Amazon Q Developer can be used to identify test scenarios before writing the actual cases. Let’s ask Amazon Q Developer to suggest test cases for the Payroll class.

In the Visual Studio Code IDE, a user has a Payroll Python class open on the right side of the editor. The Payroll class is a module used to calculate the net pay for an employee. It takes the hourly rate, hours worked, and tax rate to calculate the gross pay, tax amount, and net pay. The user asks Amazon Q Developer to list unit test scenarios for the Payroll class using the following prompt: “Can you list unit test scenarios for the Payroll class?”. Amazon Q Developer provides eight different unit test scenarios: Test valid input values, Test invalid input values, Test edge cases, Test methods behavior, Test error handling, Test data types, Test rounding behavior, and Test consistency.

Figure 5: Suggest unit test scenarios

In Figure 5, Amazon Q Developer provides a list of different scenarios specific to the Payroll class, including valid, error, and edge cases.

Using Amazon Q Developer to write unit tests

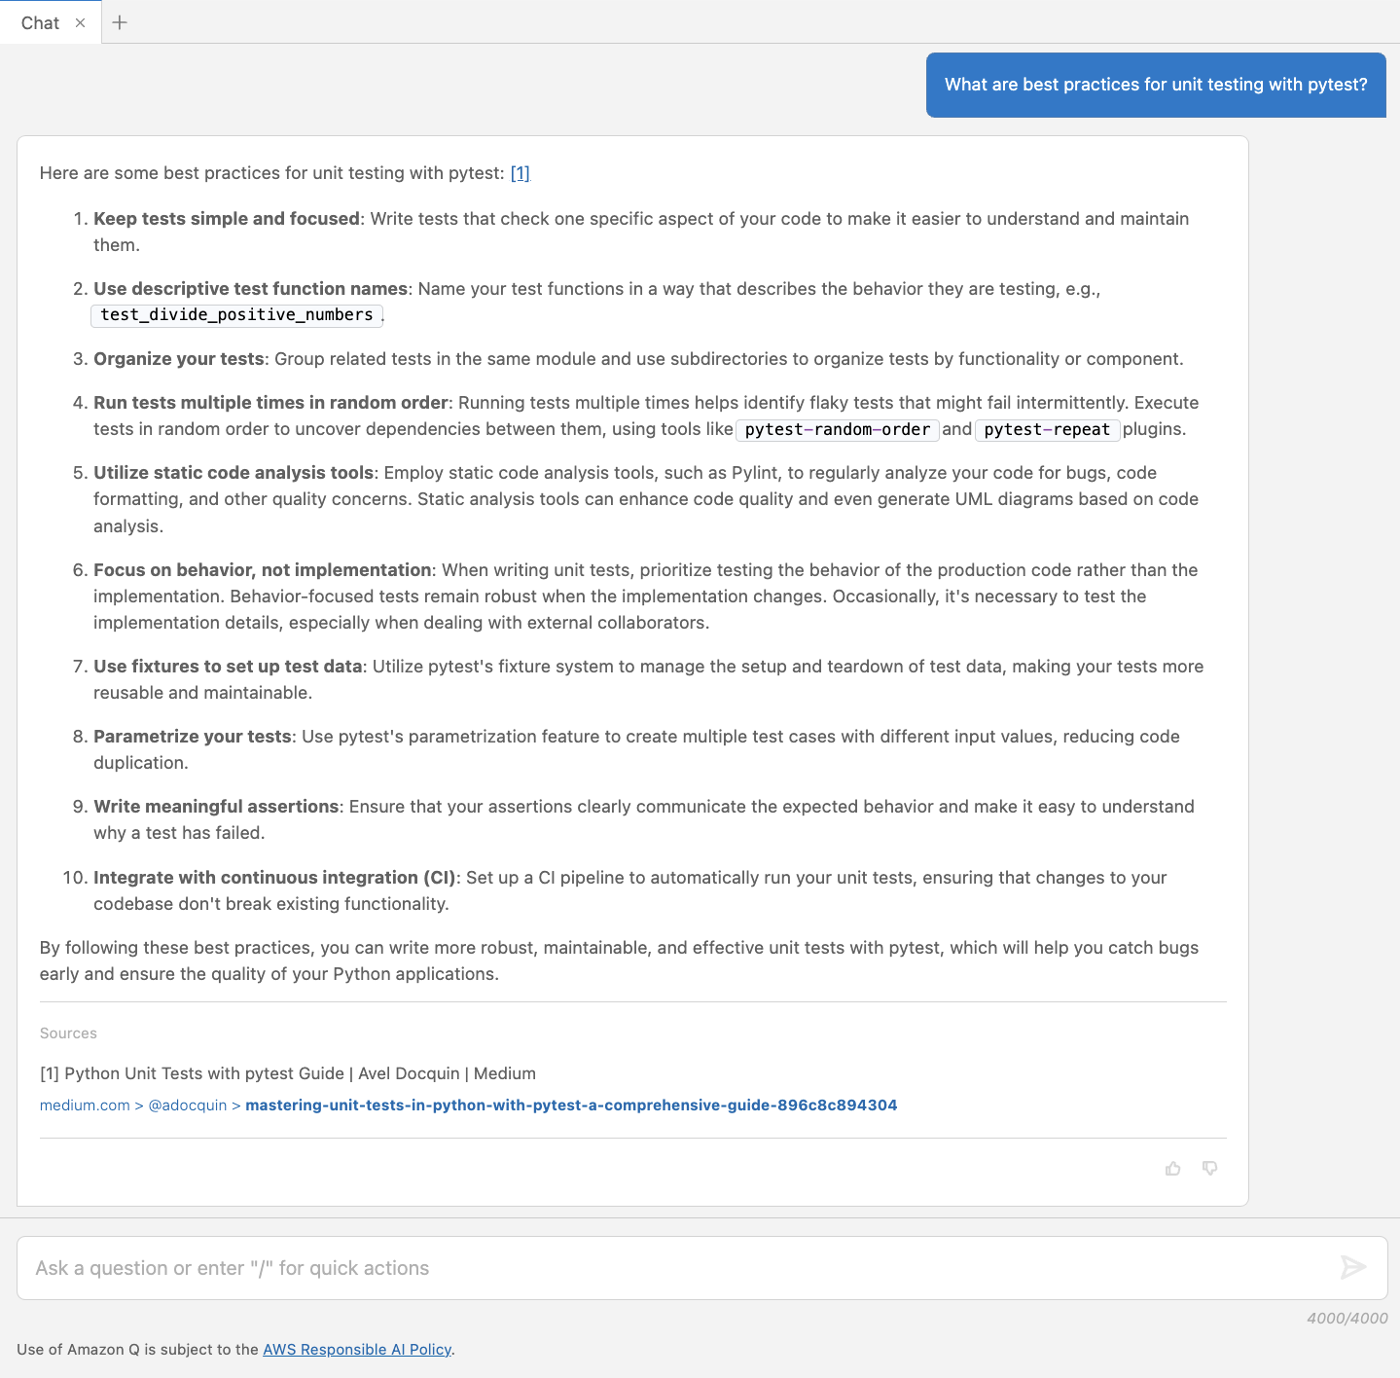
Developers can have a collaborative conversation with Amazon Q Developer, which helps to unpack the code and think through testing cases to check that important test cases are captured but also edge cases are identified. This section focuses on how to facilitate the quick generation of unit test cases, based on the cases recommended in the previous section. Let’s start with a question around best practices when writing unit tests with pytest.

In the Visual Studio Code IDE, a user asks Amazon Q Developer “What are the best practices for unit testing with pytest?”. Amazon Q Developer replies with ten best practices, including: Keep tests simple and focused, Use descriptive test function names, Organize your tests, Run tests multiple times in random order, Utilize static code analysis tools, Focus on behavior not implementation, Use fixtures to set up test data, Parameterize your tests, and Integrate with continuous integration. A source URL is also provided for a Medium article called “Python Unit Tests with pytest Guide”

Figure 6: Recommended best practices for testing with pytest

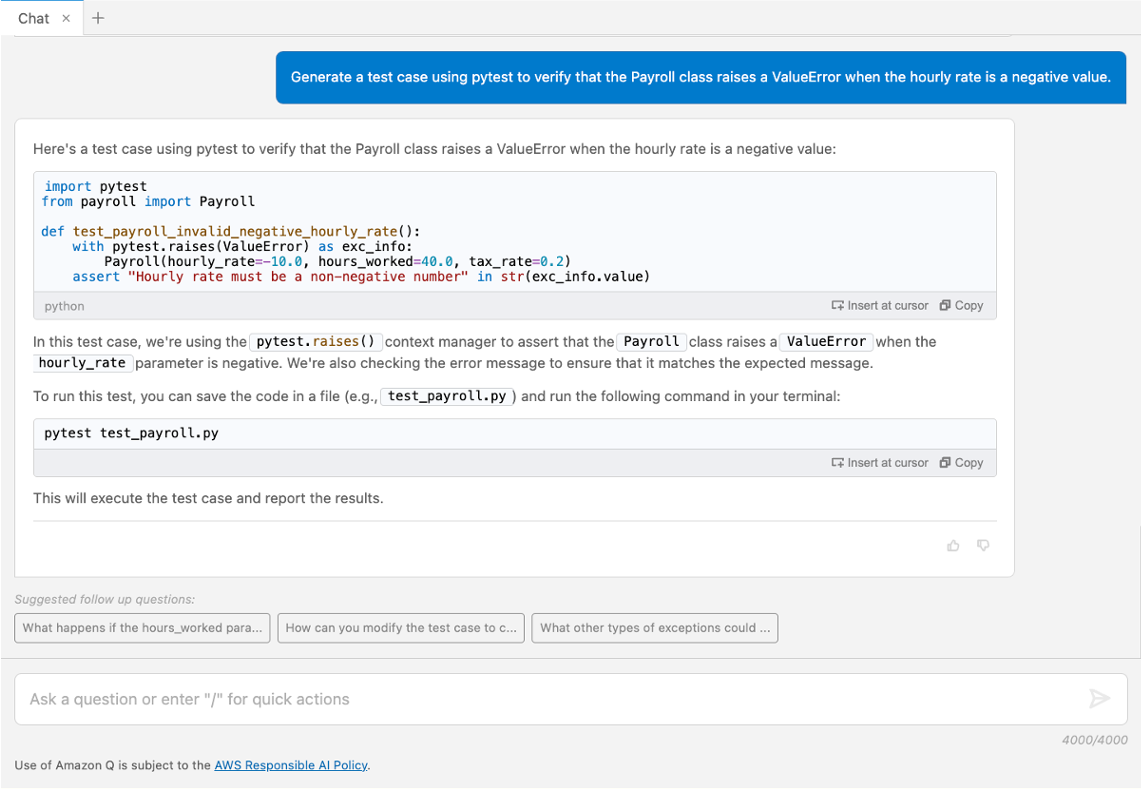
In Figure 6, Amazon Q Developer provides a list of best practices for writing effective unit tests. Let’s follow up by asking to generate one of the suggested test cases.

In the Visual Studio Code IDE, a user asks Amazon Q Developer to generate a test case using pytest to make sure that the Payroll class raises a ValueError when the hourly rate holds a negative value. Amazon Q Developer generates a code sample using the pytest.raises() context manager to satisfy the requirement. It also provides instructions on how to run the text by prefixing the test module with pytest and running the command in the terminal. The user can now click on Insert at cursor button to insert the test case into the module, and run the test.

Figure 7: Generate a unit test case

Amazon Q Developer includes code in its response which you can copy or insert directly into your file by choosing Insert at cursor. Figure 7 displays valid unit tests covering some of the suggested scenarios and best practices, such as being simple and holding descriptive naming. It also states how to run the test using a command for the terminal.

Best Practice – Provide context

Context allows Amazon Q Developer to offer tailored responses that are more in sync with the conversation. In the chat interface, the flow of the ongoing conversation and past interactions are a critical contextual element. Other ways to provide context are selecting the code-under-test, keeping any relevant files, such as test examples, open in the editor and leveraging conversation context such as asking for best practices and example test scenarios before writing the test cases.

Using Amazon Q Developer to refactor unit tests

To improve code quality, Amazon Q Developer can be used to recommend improvements and refactor parts of the code base. To illustrate Amazon Q Developer refactoring functionality, we prepared test cases for the Payroll class which deviate from some of the suggested best practices.

Example – Send to Amazon Q Refactor

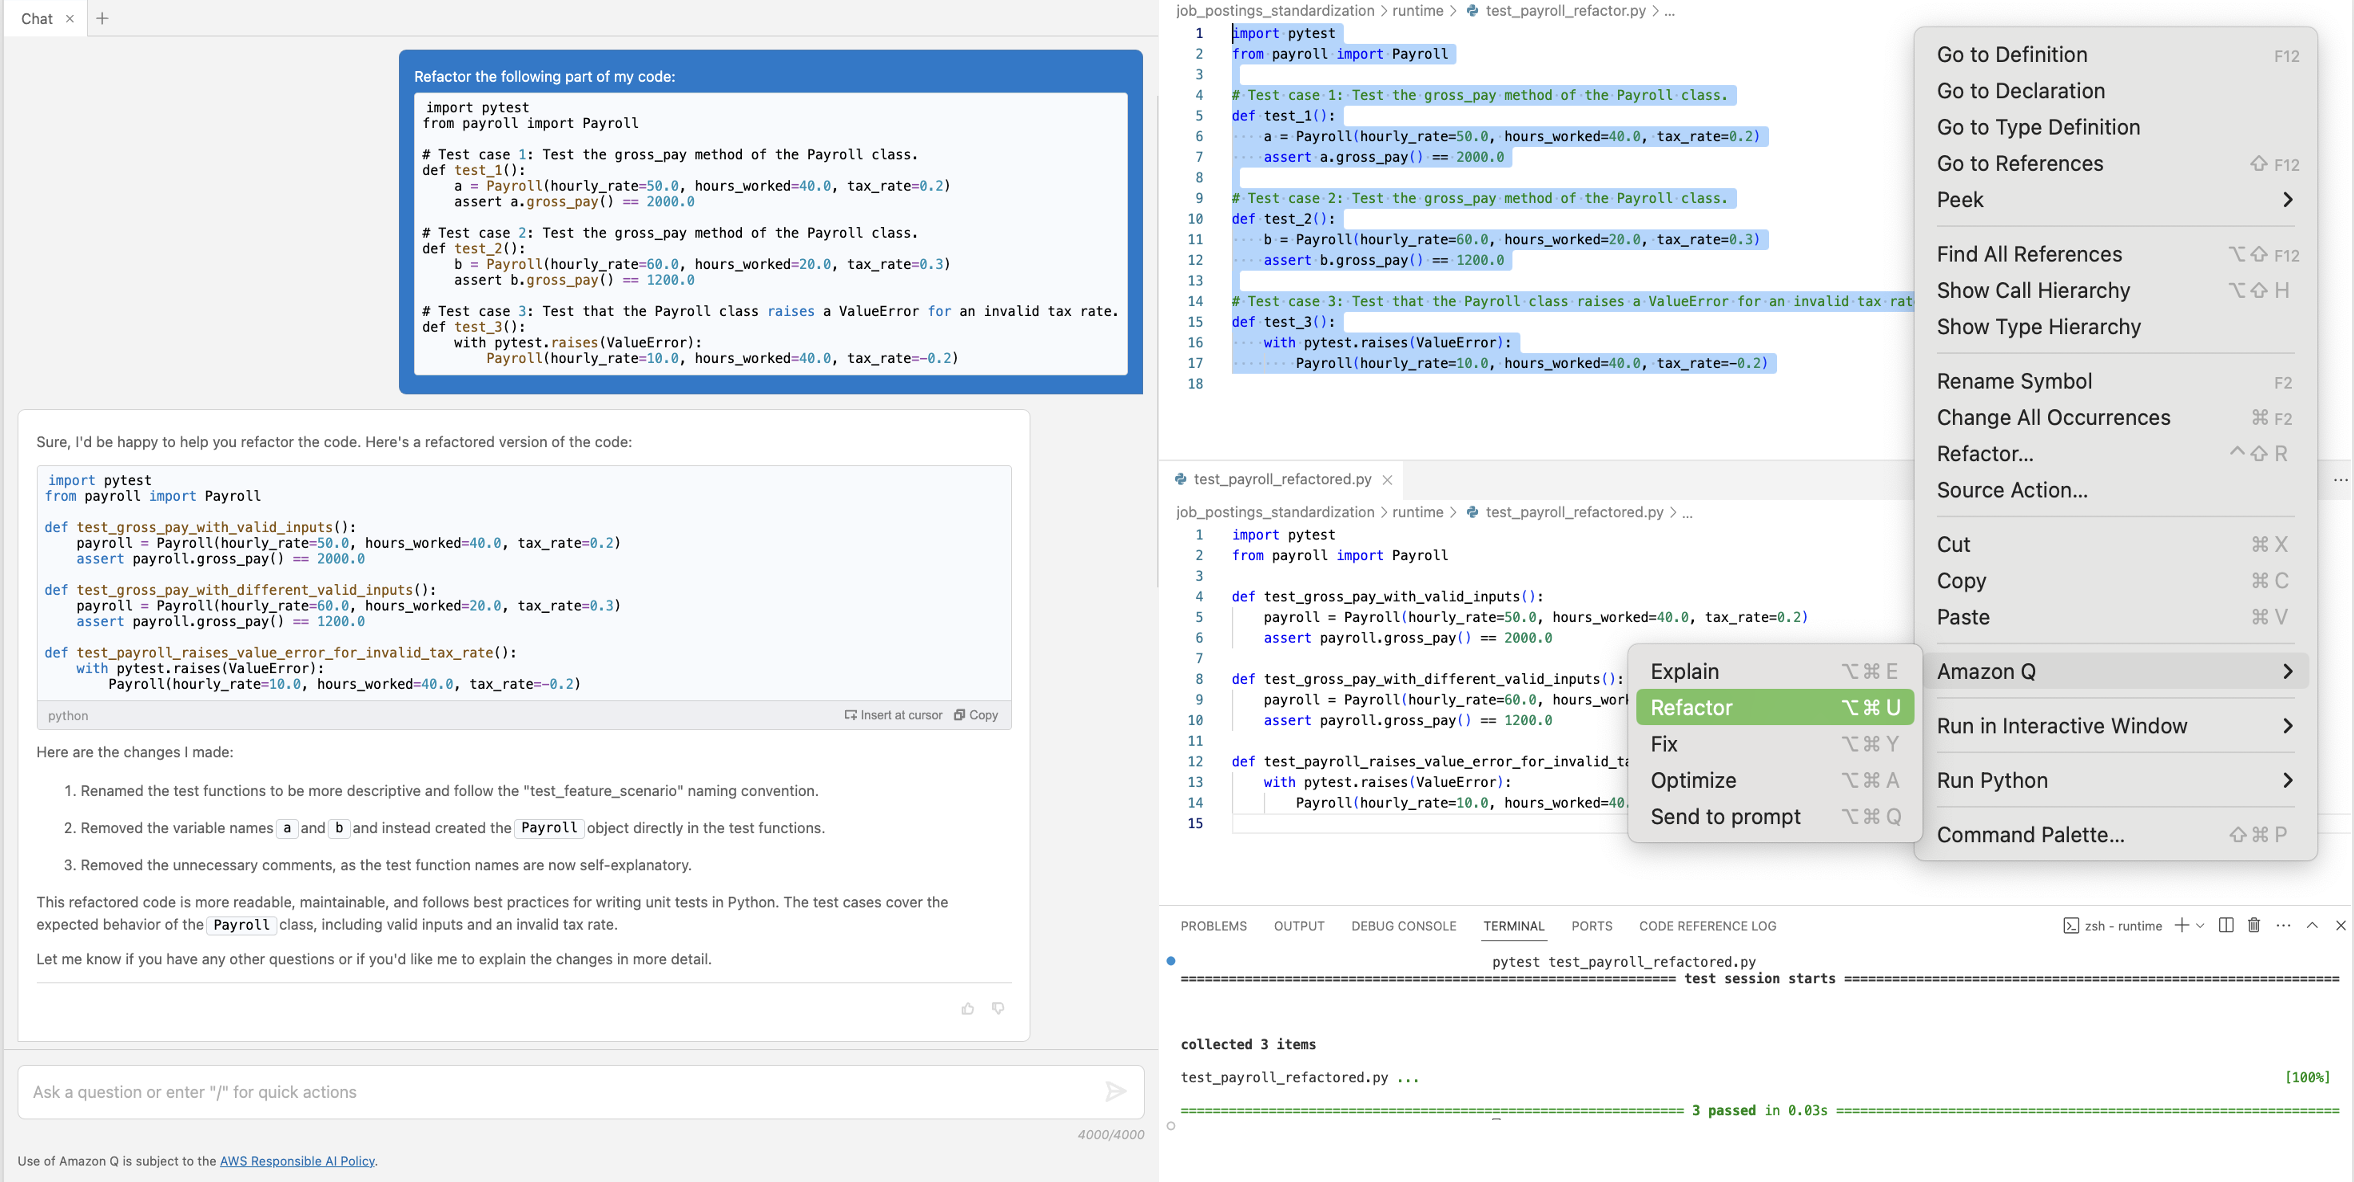
Let’s follow up by asking to refactor the code built-in Amazon Q > Refactor functionality.

In the Visual Studio Code IDE, a user selects the code in test_payroll_refactor module and asks Amazon Q Developer to refactor it via the Amazon Q Developer Refactor functionality, accessible through right click. This code contains ambiguous function and variable names, and might be hard to read without context. Amazon Q Developer then generates the refactored code and outlines the changes made: renamed test functions, removed variable names, and unnecessary comments, as functions are now self-explanatory. The user can now use the Insert at Cursor feature to add the code to the test_payroll_refactored module, and run the tests.

Figure 8: Refactor test cases

In Figure 8, the refactoring renamed the function and variable names to be more descriptive and therefore removed the comments. The recommendation is inserted in the second file to verify it runs correctly.

Best Practice – Apply human judgement and continuously interact with Amazon Q Developer

Note that code generations should always be reviewed and adjusted before used in your projects. Amazon Q Developer can provide you with initial guidance, but you might not get a perfect answer. A developer’s judgement should be applied to value usefulness of the generated code and iterations should be used to continuously improve the results.

Using Amazon Q Developer for mocking dependencies and generating sample data

More complex application architectures may require developers to mock dependencies and use sample data to test specific functionalities. The second code example contains a save_to_dynamodb_table function that writes a job_posting object into a specific Amazon DynamoDB table. This function references the TABLE_NAME environment variable to specify the name of the table in which the data should be saved.

We break down the tasks for Amazon Q Developer into three smaller steps for testing: Generate a fixture for mocking the TABLE_NAME environment variable name, generate instances of the given class to be used as test data, and generate the test.

Example – Generate fixtures

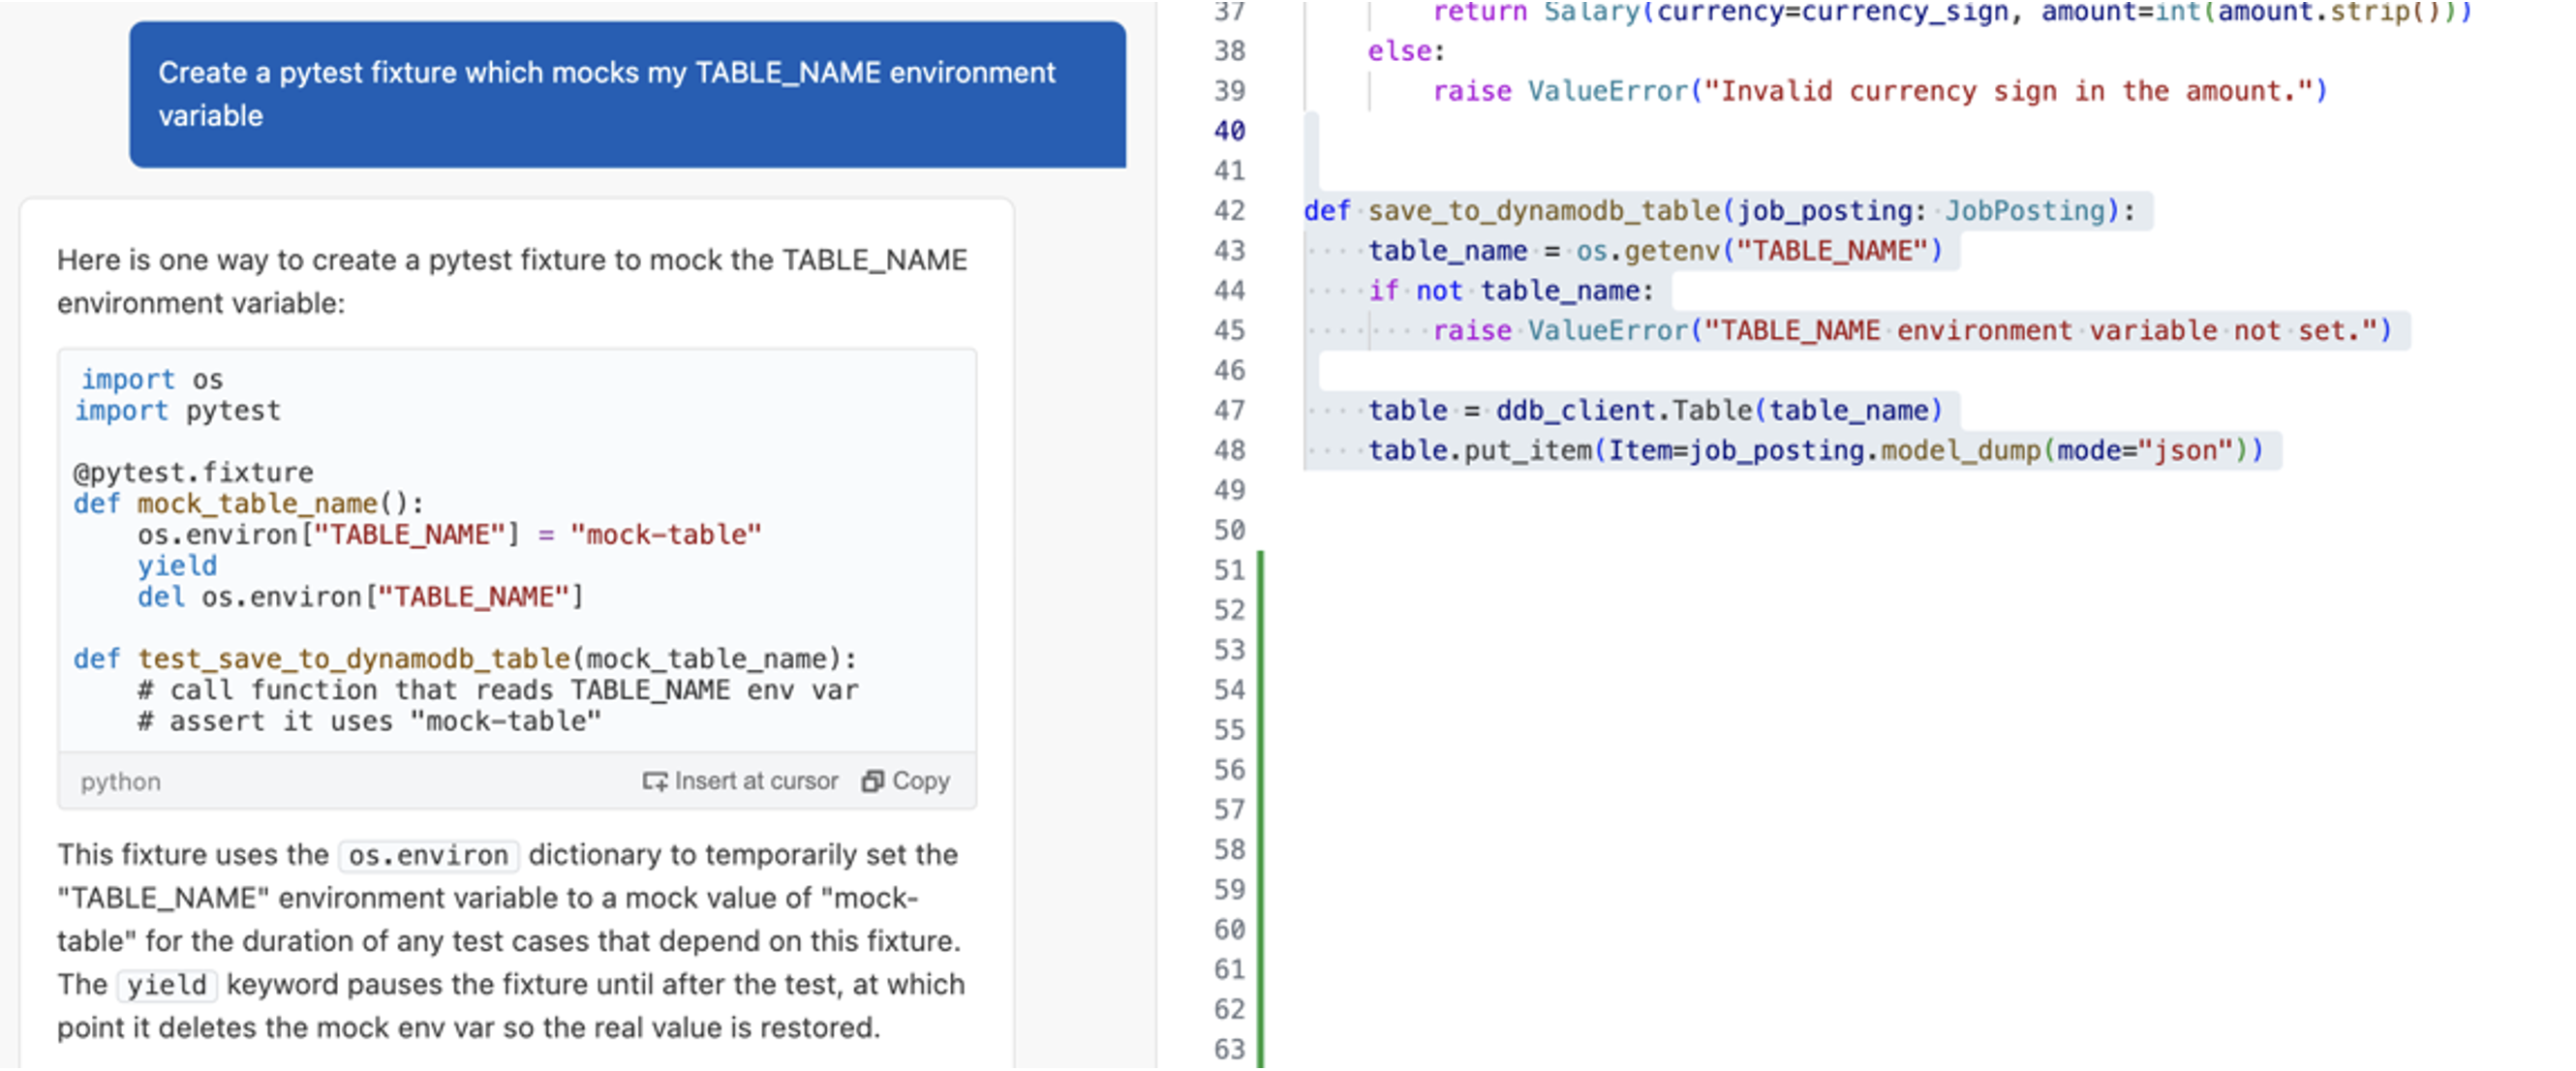
Pytest provides the capability to define fixtures to set defined, reliable, and consistent context for tests. Let’s ask Amazon Q Developer to write a fixture for the TABLE_NAME environment variable.

In the Visual Studio Code IDE, a user asks Amazon Q Developer to create a pytest fixture to mock the TABLE_NAME environment variable using the following prompt: “Create a pytest fixture which mocks my TABLE_NAME environment variable”. Amazon Q Developer replies with a code example showing how the fixture uses the os.environ dictionary to temporarily set the environment variable value to a mock value just for the duration of any test case using the fixture. The code example also includes a yield keyword to pause the fixture, and then delete the mock environment variable to restore the actual value once the test is completed.

Figure 9: Generate a pytest fixture

The result in Figure 9 shows that Amazon Q Developer generated a simple fixture for the TABLE_NAME environment variable. It provides code showing how to use the fixture in the actual test case with additional comments for its content.

Example – Generate data

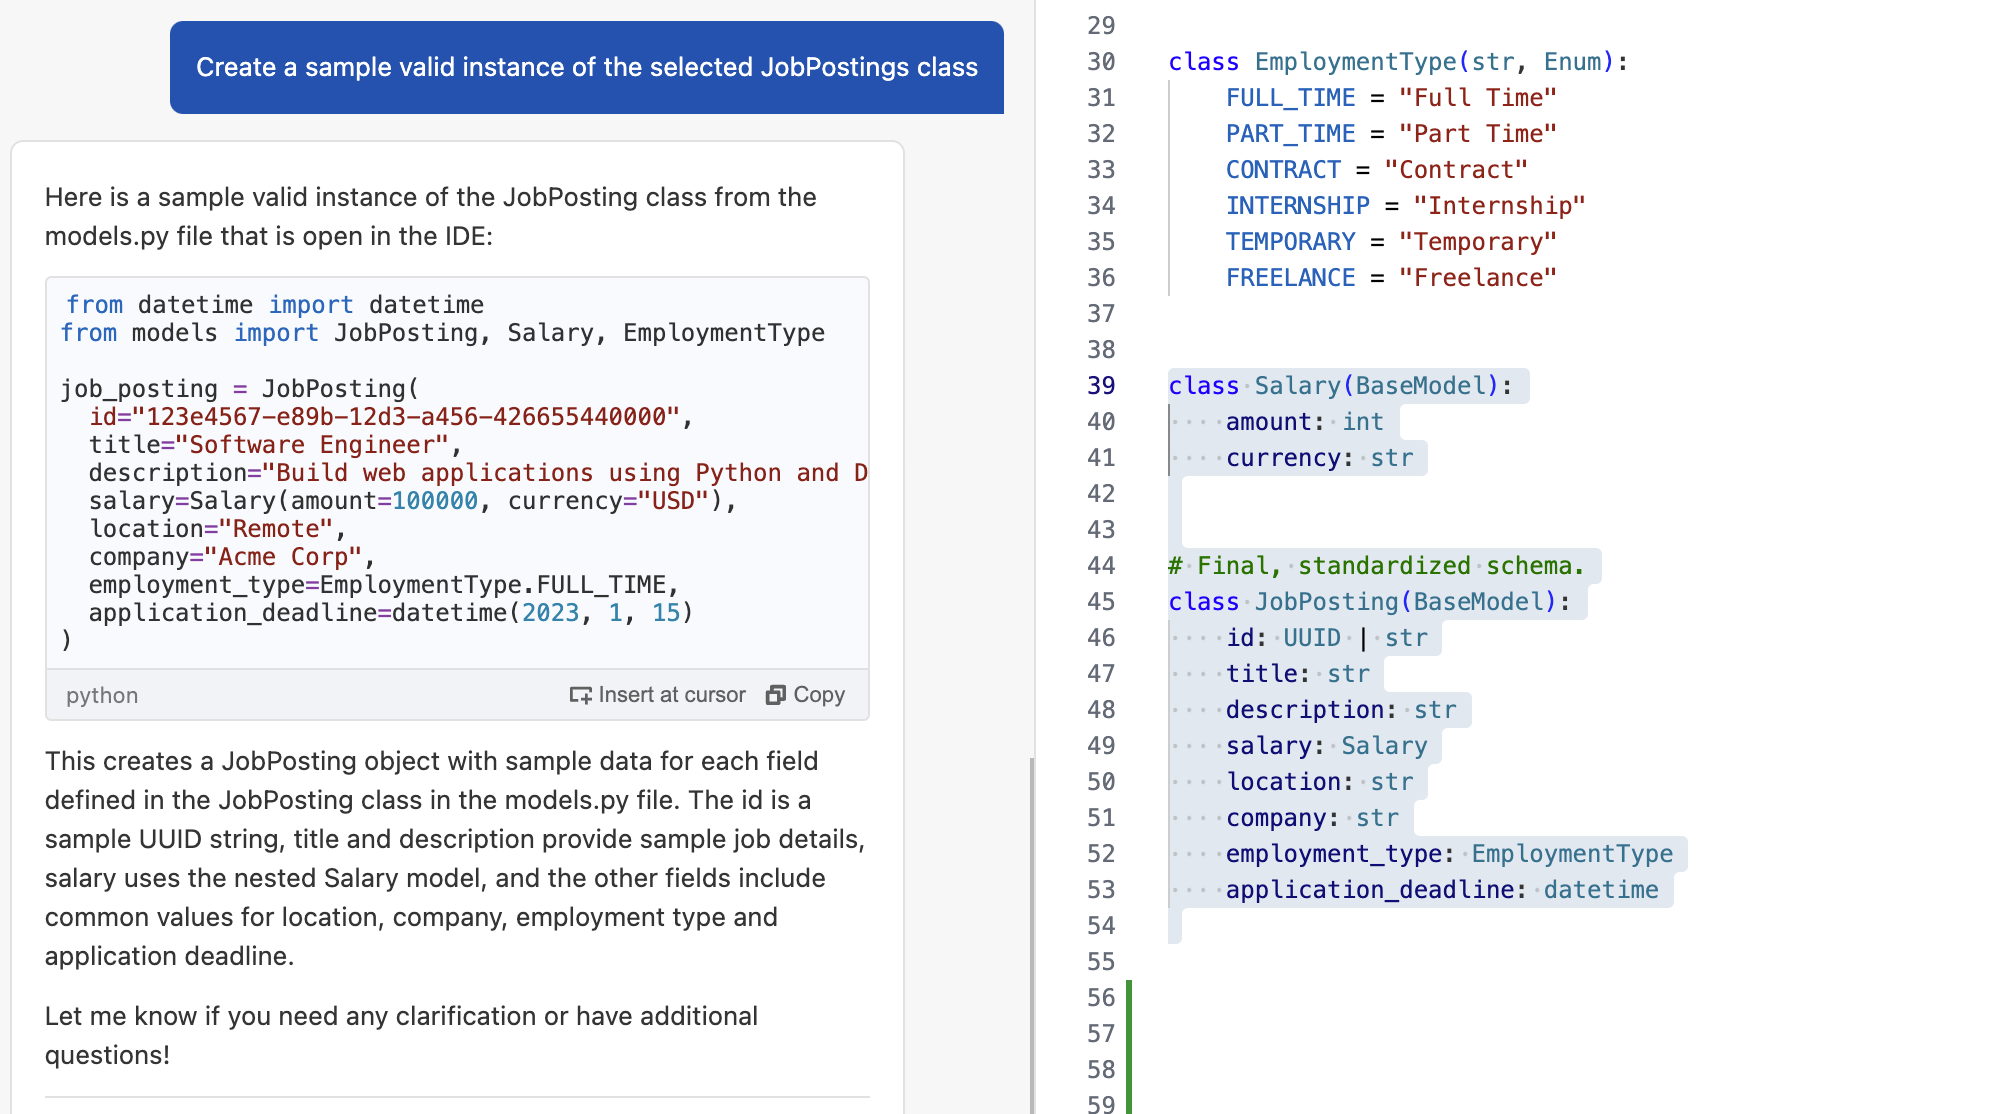
Amazon Q Developer provides capabilities that can help you generate input data for your tests based on a schema, data model, or table definition. The save_to_dynamodb_table saves an instance of the job posting class to the table. Let’s ask Amazon Q Developer to create a sample instance based on this definition.

In the Visual Studio Code IDE, a user asks Amazon Q Developer to create a sample valid instance of the selected JobPosting class using the following prompt: “Create a sample valid instance of the selected JobPostings class”. The JobPosting class includes multiple fields, including: id, title, description, salary, location, company, employment type, and application_deadline. Amazon Q Developer provides a valid snippet for the JobPosting class, incorporating a UUID for the id field, nested amount and currency for the Salary class, and generic sample values for the remaining fields.

Figure 10: Generate sample data

The answer shows a valid instance of the class in Figure 10 containing common example values for the fields.

Example – Generate unit test cases with context

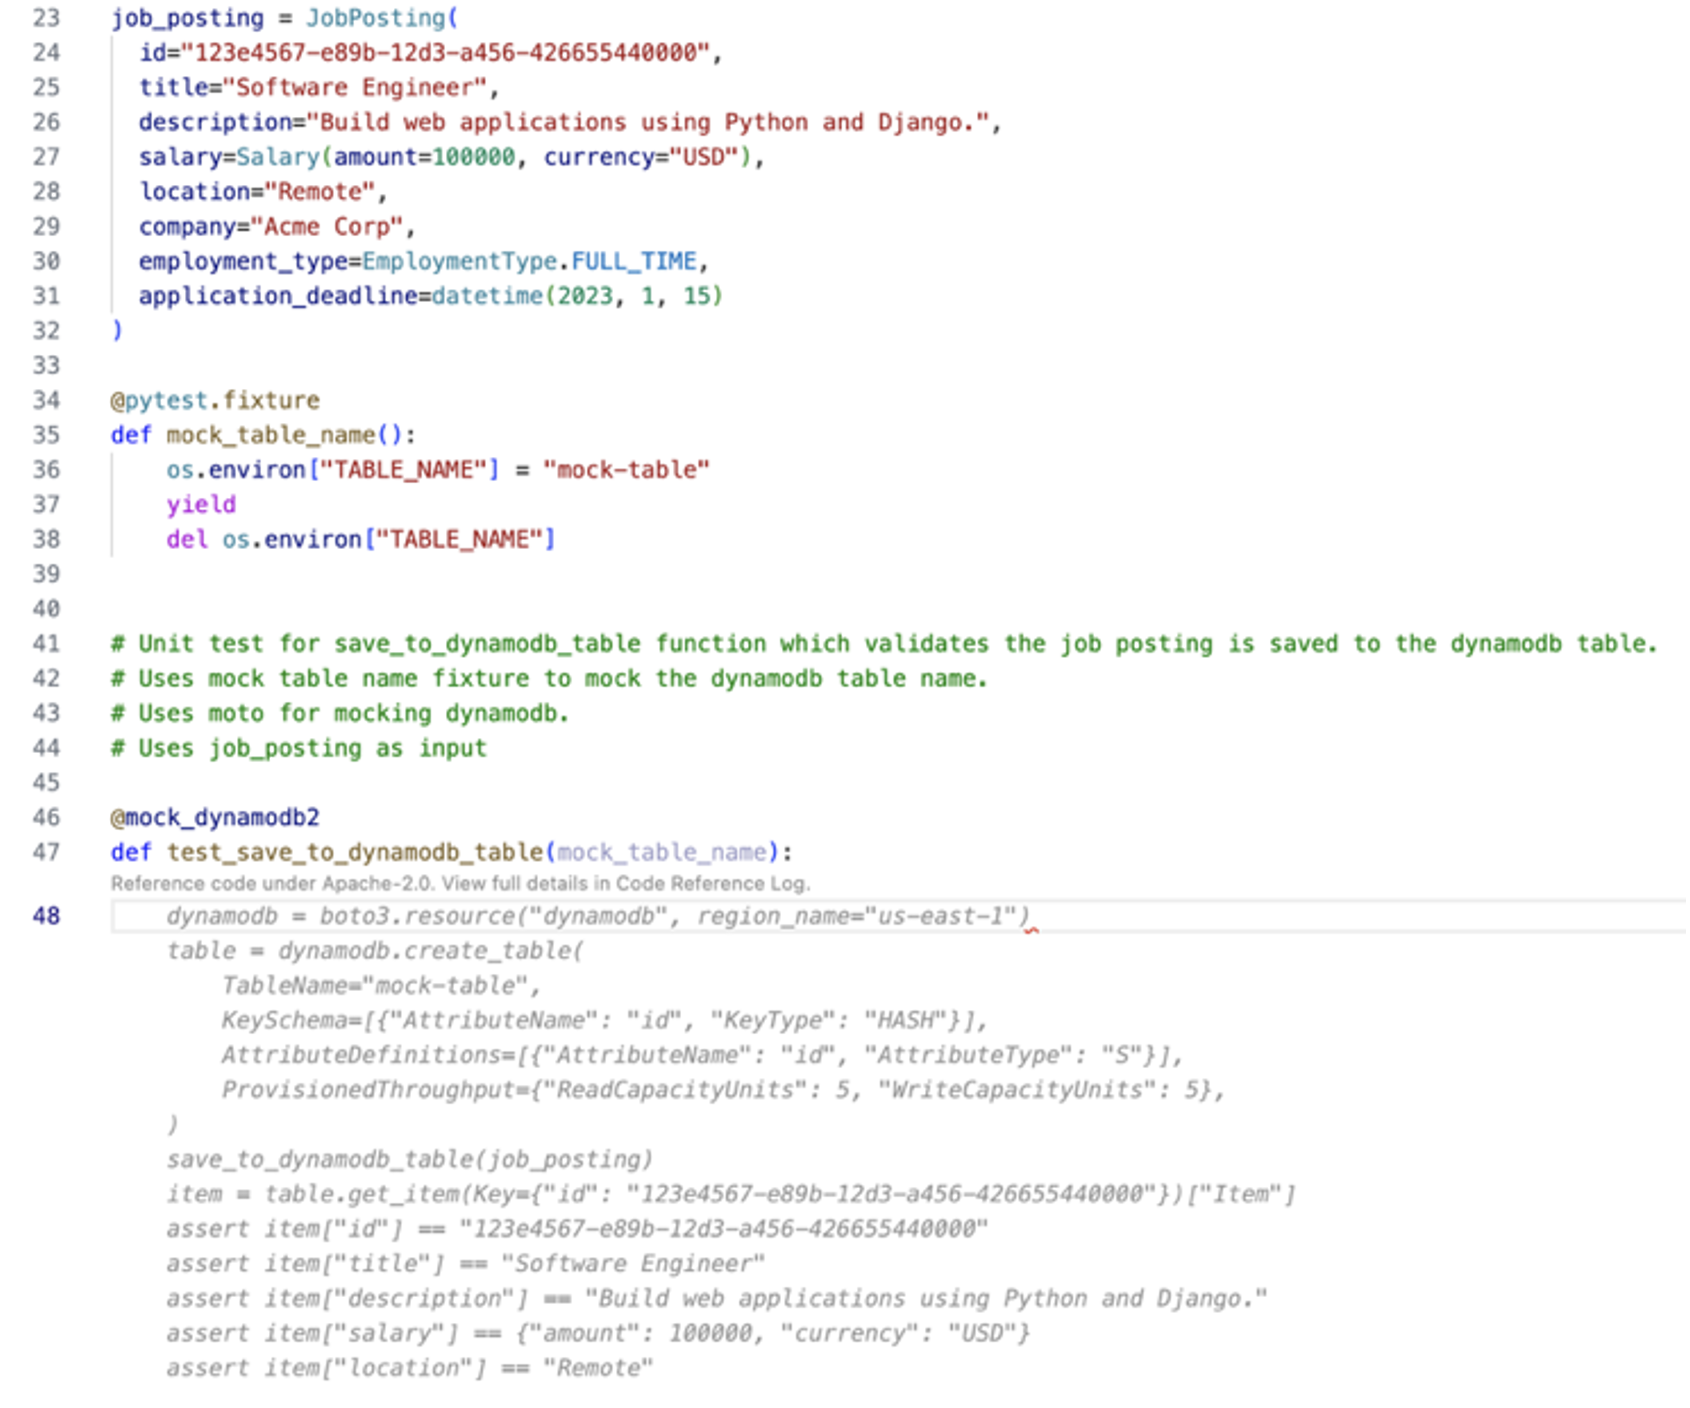
The code being tested relies on an external library, boto3. To make sure that this dependency is included, we leave a comment specifying that boto3 should be mocked using the Moto library. Additionally, we tell Amazon Q Developer to consider the test instance named job_posting and the fixture named mock_table_name for reference. Developers can now provide a prompt to generate the test case using the context from previous tasks or use comments as inline prompts to generate the test within the test file itself.

In the Visual Studio Code IDE, a user is leveraging inline prompts to generate an autocomplete suggestion from Amazon Q Developer. The inline prompt response is trying to fill out the test_save_to_dynamodb_table function with a mock test asserting the previous JobPosting fields. The user can decide to accept or reject the provided code completion suggestion.

Figure 11: Inline prompts for generating unit test case

Figure 11 shows the recommended code using inline prompts, which can be accepted as the unit test for the save_to_dynamodb_table function.

Best Practice – Break down larger tasks into smaller ones

For cases where Amazon Q Developer does not have much context or example code to refer to, such as writing unit tests from scratch, it is helpful to break down the tasks into smaller tasks. Amazon Q Developer will get more context with each step and can result in more effective responses.

Conclusion

Amazon Q Developer is a powerful tool that simplifies the process of writing and executing unit tests for your application. The examples provided in this post demonstrated that it can be a helpful companion throughout different stages of your unit test process. From initial learning to investigation and writing of test cases, the Chat, Generate, and Refactor capabilities allow you to speed up and improve your test generation. Using clear and concise prompts, context, an iterative approach, and small scoped tasks to interact with Amazon Q Developer improves the generated answers.

To learn more about Amazon Q Developer, see the following resources:

About the authors

Iris Kraja

Iris is a Cloud Application Architect at AWS Professional Services based in New York City. She is passionate about helping customers design and build modern AWS cloud native solutions, with a keen interest in serverless technology, event-driven architectures and DevOps. Outside of work, she enjoys hiking and spending as much time as possible in nature.

Svenja Raether

Svenja is a Cloud Application Architect at AWS Professional Services based in Munich.

Davide Merlin

Davide is a Cloud Application Architect at AWS Professional Services based in Jersey City. He specializes in backend development of cloud-native applications, with a focus on API architecture. In his free time, he enjoys playing video games, trying out new restaurants, and watching new shows.

Leveraging Amazon Q Developer for Efficient Code Debugging and Maintenance

Post Syndicated from Dr. Rahul Sharad Gaikwad original https://aws.amazon.com/blogs/devops/leveraging-amazon-q-developer-for-efficient-code-debugging-and-maintenance/

In this post, we guide you through five common components of efficient code debugging. We also show you how Amazon Q Developer can significantly reduce the time and effort required to manually identify and fix errors across numerous lines of code. With Amazon Q Developer on your side, you can focus on other aspects of software development, such as design and innovation. This leads to faster development cycles and more frequent releases, as you as a software developer can allocate less time to debugging and more time to building new features and functionality.

Debugging is a crucial part of the software development process. It involves identifying and fixing errors or bugs in the code to ensure that it runs smoothly and efficiently in the production environment. Traditionally, debugging has been a time-consuming and labor-intensive process, requiring developers to manually search through lines of code to investigate and subsequently fix errors. With Amazon Q Developer, a generative AI–powered assistant that helps you learn, plan, create, deploy, and securely manage applications faster, the debugging process becomes more efficient and streamlined. This enables you to easily understand the code, detect anomalies, fix issues and even automatically generate the test cases for your application code.

Let’s consider the following code example, which utilizes Amazon Bedrock, Amazon Polly, and Amazon Simple Storage Service (Amazon S3) to generate a speech explanation of a given prompt. A prompt is the message sent to a model in order to generate a response. It constructs a JSON payload with the prompt (for example – “explain black holes to 8th graders”) and configuration for the Claude model, and invokes the model via the Bedrock Runtime API. Amazon Polly converts the Large Language Model (LLM) response into an audio output format which is then uploaded to an Amazon S3 bucket location:

Sample Code Snippet:

import boto3
import json
# Define boto clients
brt = boto3.client(service_name='bedrock-runtime')
polly = boto3.client('polly')
s3 = boto3.client('s3')
body = json.dumps({
"prompt": "\n\nHuman: explain black holes to 8th graders\n\nAssistant:",
"max_tokens_to_sample": 300,
"temperature": 0.1,
"top_p": 0.9,
})
# Define variable
modelId = 'anthropic.claude-v2'
accept = 'application/json'
contentType = 'application/json'
response = brt.invoke_model(body=body, modelId=modelId, accept=accept, contentType=contentType)
response_body = json.loads(response.get('body').read())
# Print response
print(response_body.get('completion'))
# Send response to Polly
polly_response = polly.synthesize_speech(
Text=response_body.get('completion'),
OutputFormat='mp3',
VoiceId='Joanna'
)
# Write audio to file
with open('output.mp3', 'wb') as file:
file.write(polly_response['AudioStream'].read())
# Upload file to S3 bucket
s3.upload_file('output.mp3', '<REPLACE_WITH_YOUR_BUCKET_NAME>', 'speech.mp3')

Top common ways to debug code:

1. Code Explanation:

The first step in debugging your code is to understand what the code is doing. Very often you have to build upon code from others. Amazon Q Developer comes with an inbuilt feature that allows it to quickly explain the selected code and identify the main components and functions. This feature utilizes natural language processing (NLP) and summarization capability of LLMs, making your code easy to understand, and helping you identify potential issues. To gain deeper insights into your codebase, simply select your code, right-click and select ‘Send to Amazon Q’ option from menu. Finally, click on “Explain” option.

Image showing the interface for sending selected code to Amazon Q Developer for explanation

Amazon Q Developer generates an explanation of the code, highlighting the key components and functions. You can then use this summary to quickly identify potential issues and minimize your debugging efforts. It demonstrates how Amazon Q Developer accepts your code as input and the summarizes it for you. It explains the code in a natural language, which can help developers understand and debug the code.

If you have any follow-up question regarding the given explanation, you can also ask Amazon Q Developer for more in-depth review of a specific task. With respect to the code context, Amazon Q Developer automatically understands the existing code functionality and provides more insights. We ask Amazon Q Developer to explain how the Amazon Polly service is being used for synthesizing in the sample code snippet. It provides detailed step-by-step clarification from the retrieval to the upload process. Using this approach, you can ask any clarifying questions similar to asking a colleague to help you better understand a topic.

Amazon Q Developer explains how Polly is used to Synthesize in the given code

2. Amplify debugging with Logs

The sample code is deficient in terms of support for debugging including proper exception handling mechanisms. This makes it difficult to identify and handle issues during the execution or runtime of the application, further causing delays in the overall development process. You can instruct Amazon Q Developer to add a new code block for debugging your application against potential failures. Amazon Q Developer analyzes the existing code and then recommends to add a new code snippet to include printing and logging of debug messages and exception handling. It embeds ‘try-except’ blocks to catch potential exceptions that may occur. You use the recommended code after reviewing and modifying it. For example, you need to update the variable REPLACE_WITH_YOUR_BUCKET_NAME with your actual Amazon S3 bucket name.

With Amazon Q, you seamlessly enhance your codebase by selecting specific code segments and providing them as prompts. This enables you to explore suggestions for incorporating the required exception handling mechanisms or strategic logging statements.

Amazon Q Developer interface illustrating the addition of debugging code to the original code snippet

Logs are an essential tool for debugging your application code. They allow you to track the execution of your code and identify where errors are occurring. With Amazon Q Developer, you can view and analyze log data from your application, and identify issues and errors that may not be immediately apparent from the code. It demonstrates that the given code does not have the logging statements embedded.

You can provide a prompt to Amazon Q Developer in the chat window asking it to write a code to enable logging and add log statements. This will automatically add logging statements wherever needed. It is useful to log inputs, outputs, and errors when making API calls or invoking models. You may copy the entire recommended code to the clipboard, review it, and then modify as needed. For example, you can decide which logging level you want to use, INFO or DEBUG.

Example of logging statements inserted into the code by Amazon Q Developer for enhanced debugging

3. Anomaly Detection

Another powerful use case for Amazon Q Developer is anomaly detection in your application code. Amazon Q Developer uses machine learning algorithms to identify unusual patterns in your code and highlight potential issues. It can detect issues that may be difficult to detect, such as an array out of bounds, infinite loops, or concurrency issues. For demonstration purposes, we intentionally introduce a simple anomaly in the code. We ask Amazon Q Developer to detect the anomaly in the code when attempting to generate text from the response. A simple prompt about detecting anomalies in the given code generates a useful output. It is able to detect the anomaly in the ‘response_body’ dictionary. Additionally, Amazon Q Developer recommends best practices to check the status code and handle the errors with a code snippet.

Process of submitting selected code to Amazon Q Developer for automated bug fixing

With code anomaly detection at your fingertips, you can promptly identify issues that may be impacting the application’s performance or user experience.

4. Automated Bug Fixing

After conducting all the necessary analysis, you can use Amazon Q Developer to fix bugs and issues in the code. Amazon Q Developer’s automated bug-fixing feature saves you hours you would otherwise spend on debugging and testing the code without its help. Starting with the code example which has an anomaly, you can identify and fix the code issue by simply selecting the code and sending it to Amazon Q Developer to apply fixes.

Process of submitting selected code to Amazon Q Developer for automated bug fixing

Amazon Q Developer identifies and suggests various ways to fix common issues in your code, such as syntax errors, logical errors, and performance issues. It can also recommend optimizations and improvements to your code, helping you to deliver a better user experience and improve your application’s performance.

5. Automated Test Case Generation

Testing is an integral part of code development and debugging. Running high quality test cases improve the quality of the code. With Amazon Q Developer, you can automatically generate the test cases quickly and easily. Amazon Q Developer uses its Large Language Model core to generate test cases based on your code, identifying potential issues and ensuring that your code is comprehensive and reliable.

With automated test case generation, you save time and effort while testing your code, ensuring that it is robust and reliable. A natural language prompt is sent to Amazon Q Developer to suggest test cases for given application code. You can notice that Amazon Q Developer provides a list of possible test cases that can aid in debugging and generating further test cases.

Recommendations and solutions provided by Amazon Q Developer to address issues in the code blocks

After receiving suggestions for test cases, you can also ask Amazon Q Developer to generate code snippet for some or all of the identified test cases.

Test cases proposed by Amazon Q Developer for evaluating the example application code

Conclusion:

Amazon Q Developer revolutionizes the debugging process for developers by leveraging advanced and natural language understanding and generative AI capabilities. From explaining and summarizing code to detecting anomalies, implementing automatic bug fixes, and generating test cases, Amazon Q Developer streamlines common aspects of debugging. Developers can now spend less time manually hunting for errors and more time innovating and building features. By harnessing the power of Amazon Q, organizations can accelerate development cycles, improve code quality, and deliver superior software experiences to their customers.

To get started with Amazon Q Developer for debugging today navigate to Amazon Q Developer in IDE and simply start asking questions about debugging. Additionally, explore Amazon Q Developer workshop for additional hands-on use cases.

For any inquiries or assistance with Amazon Q Developer, please reach out to your AWS account team.

About the authors:

Dr. Rahul Sharad Gaikwad

Dr. Rahul is a Lead DevOps Consultant at AWS, specializing in migrating and modernizing customer workloads on the AWS Cloud. He is a technology enthusiast with a keen interest in Generative AI and DevOps. He received his Ph.D. in AIOps in 2022. He is recipient of the Indian Achievers’ Award (2024), Best PhD Thesis Award (2024), Research Scholar of the Year Award (2023) and Young Researcher Award (2022).

Nishant Dhiman

Nishant is a Senior Solutions Architect at AWS with an extensive background in Serverless, Generative AI, Security and Mobile platform offerings. He is a voracious reader and a passionate technologist. He loves to interact with customers and believes in giving back to community by learning and sharing. Outside of work, he likes to keep himself engaged with podcasts, calligraphy and music.

Announcing Llama 3.1 405B, 70B, and 8B models from Meta in Amazon Bedrock

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/announcing-llama-3-1-405b-70b-and-8b-models-from-meta-in-amazon-bedrock/

Today, we are announcing the availability of Llama 3.1 models in Amazon Bedrock. The Llama 3.1 models are Meta’s most advanced and capable models to date. The Llama 3.1 models are a collection of 8B, 70B, and 405B parameter size models that demonstrate state-of-the-art performance on a wide range of industry benchmarks and offer new capabilities for your generative artificial intelligence (generative AI) applications.

All Llama 3.1 models support a 128K context length (an increase of 120K tokens from Llama 3) that has 16 times the capacity of Llama 3 models and improved reasoning for multilingual dialogue use cases in eight languages, including English, German, French, Italian, Portuguese, Hindi, Spanish, and Thai.

You can now use three new Llama 3.1 models from Meta in Amazon Bedrock to build, experiment, and responsibly scale your generative AI ideas:

  • Llama 3.1 405B (preview) is the world’s largest publicly available large language model (LLM) according to Meta. The model sets a new standard for AI and is ideal for enterprise-level applications and research and development (R&D). It is ideal for tasks like synthetic data generation where the outputs of the model can be used to improve smaller Llama models and model distillations to transfer knowledge to smaller models from the 405B model. This model excels at general knowledge, long-form text generation, multilingual translation, machine translation, coding, math, tool use, enhanced contextual understanding, and advanced reasoning and decision-making. To learn more, visit the AWS Machine Learning Blog about using Llama 3.1 405B to generate synthetic data for model distillation.
  • Llama 3.1 70B is ideal for content creation, conversational AI, language understanding, R&D, and enterprise applications. The model excels at text summarization and accuracy, text classification, sentiment analysis and nuance reasoning, language modeling, dialogue systems, code generation, and following instructions.
  • Llama 3.1 8B is best suited for limited computational power and resources. The model excels at text summarization, text classification, sentiment analysis, and language translation requiring low-latency inferencing.

Meta measured the performance of Llama 3.1 on over 150 benchmark datasets that span a wide range of languages and extensive human evaluations. As you can see in the following chart, Llama 3.1 outperforms Llama 3 in every major benchmarking category.

To learn more about Llama 3.1 features and capabilities, visit the Llama 3.1 Model Card from Meta and Llama models in the AWS documentation.

You can take advantage of Llama 3.1’s responsible AI capabilities, combined with the data governance and model evaluation features of Amazon Bedrock to build secure and reliable generative AI applications with confidence.

  • Guardrails for Amazon Bedrock – By creating multiple guardrails with different configurations tailored to specific use cases, you can use Guardrails to promote safe interactions between users and your generative AI applications by implementing safeguards customized to your use cases and responsible AI policies. With Guardrails for Amazon Bedrock, you can continually monitor and analyze user inputs and model responses that might violate customer-defined policies, detect hallucination in model responses that are not grounded in enterprise data or are irrelevant to the user’s query, and evaluate across different models including custom and third-party models. To get started, visit Create a guardrail in the AWS documentation.
  • Model evaluation on Amazon Bedrock – You can evaluate, compare, and select the best Llama models for your use case in just a few steps using either automatic evaluation or human evaluation. With model evaluation on Amazon Bedrock, you can choose automatic evaluation with predefined metrics such as accuracy, robustness, and toxicity. Alternatively, you can choose human evaluation workflows for subjective or custom metrics such as relevance, style, and alignment to brand voice. Model evaluation provides built-in curated datasets or you can bring in your own datasets. To get started, visit Get started with model evaluation in the AWS documentation.

To learn more about how to keep your data and applications secure and private in AWS, visit the Amazon Bedrock Security and Privacy page.

Getting started with Llama 3.1 models in Amazon Bedrock
If you are new to using Llama models from Meta, go to the Amazon Bedrock console and choose Model access on the bottom left pane. To access the latest Llama 3.1 models from Meta, request access separately for Llama 3.1 8B Instruct, Llama 3.1 70B Instruct, or Llama 3.1 405B Instruct.

To request to be considered for access to the preview of Llama 3.1 405B in Amazon Bedrock, contact your AWS account team or submit a support ticket via the AWS Management Console. When creating the support ticket, select Amazon Bedrock as the Service and Models as the Category.

To test the Llama 3.1 models in the Amazon Bedrock console, choose Text or Chat under Playgrounds in the left menu pane. Then choose Select model and select Meta as the category and Llama 3.1 8B Instruct, Llama 3.1 70B Instruct, or Llama 3.1 405B Instruct as the model.

In the following example I selected the Llama 3.1 405B Instruct model.

By choosing View API request, you can also access the model using code examples in the AWS Command Line Interface (AWS CLI) and AWS SDKs. You can use model IDs such as meta.llama3-1-8b-instruct-v1, meta.llama3-1-70b-instruct-v1 , or meta.llama3-1-405b-instruct-v1.

Here is a sample of the AWS CLI command:

aws bedrock-runtime invoke-model \
  --model-id meta.llama3-1-405b-instruct-v1:0 \
--body "{\"prompt\":\" [INST]You are a very intelligent bot with exceptional critical thinking[/INST] I went to the market and bought 10 apples. I gave 2 apples to your friend and 2 to the helper. I then went and bought 5 more apples and ate 1. How many apples did I remain with? Let's think step by step.\",\"max_gen_len\":512,\"temperature\":0.5,\"top_p\":0.9}" \
  --cli-binary-format raw-in-base64-out \
  --region us-east-1 \
  invoke-model-output.txt

You can use code examples for Llama models in Amazon Bedrock using AWS SDKs to build your applications using various programming languages. The following Python code examples show how to send a text message to Llama using the Amazon Bedrock Converse API for text generation.

import boto3
from botocore.exceptions import ClientError

# Create a Bedrock Runtime client in the AWS Region you want to use.
client = boto3.client("bedrock-runtime", region_name="us-east-1")

# Set the model ID, e.g., Llama 3 8b Instruct.
model_id = "meta.llama3-1-405b-instruct-v1:0"

# Start a conversation with the user message.
user_message = "Describe the purpose of a 'hello world' program in one line."
conversation = [
    {
        "role": "user",
        "content": [{"text": user_message}],
    }
]

try:
    # Send the message to the model, using a basic inference configuration.
    response = client.converse(
        modelId=model_id,
        messages=conversation,
        inferenceConfig={"maxTokens": 512, "temperature": 0.5, "topP": 0.9},
    )

    # Extract and print the response text.
    response_text = response["output"]["message"]["content"][0]["text"]
    print(response_text)

except (ClientError, Exception) as e:
    print(f"ERROR: Can't invoke '{model_id}'. Reason: {e}")
    exit(1)

You can also use all Llama 3.1 models (8B, 70B, and 405B) in Amazon SageMaker JumpStart. You can discover and deploy Llama 3.1 models with a few clicks in Amazon SageMaker Studio or programmatically through the SageMaker Python SDK. You can operate your models with SageMaker features such as SageMaker Pipelines, SageMaker Debugger, or container logs under your virtual private cloud (VPC) controls, which help provide data security.

The fine-tuning for Llama 3.1 models in Amazon Bedrock and Amazon SageMaker JumpStart will be coming soon. When you build fine-tuned models in SageMaker JumpStart, you will also be able to import your custom models into Amazon Bedrock. To learn more, visit Meta Llama 3.1 models are now available in Amazon SageMaker JumpStart on the AWS Machine Learning Blog.

For customers who want to deploy Llama 3.1 models on AWS through self-managed machine learning workflows for greater flexibility and control of underlying resources, AWS Trainium and AWS Inferentia-powered Amazon Elastic Compute Cloud (Amazon EC2) instances enable high performance, cost-effective deployment of Llama 3.1 models on AWS. To learn more, visit AWS AI chips deliver high performance and low cost for Meta Llama 3.1 models on AWS in the AWS Machine Learning Blog.

To celebrate this launch, Parkin Kent, Business Development Manager at Meta, talks about the power of the Meta and Amazon collaboration, highlighting how Meta and Amazon are working together to push the boundaries of what’s possible with generative AI.

Discover how businesses are leveraging Llama models in Amazon Bedrock to harness the power of generative AI. Nomura, a global financial services group spanning 30 countries and regions, is democratizing generative AI across its organization using Llama models in Amazon Bedrock.

Now available
Llama 3.1 8B and 70B models from Meta are generally available and Llama 450B model is preview today in Amazon Bedrock in the US West (Oregon) Region. To request to be considered for access to the preview of Llama 3.1 405B in Amazon Bedrock, contact your AWS account team or submit a support ticket. Check the full Region list for future updates. To learn more, check out the Llama in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give Llama 3.1 a try in the Amazon Bedrock console today, and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

Visit our community.aws site to find deep-dive technical content and to discover how our Builder communities are using Amazon Bedrock in their solutions. Let me know what you build with Llama 3.1 in Amazon Bedrock!

— Channy

AWS announces workspace context awareness for Amazon Q Developer chat

Post Syndicated from Will Matos original https://aws.amazon.com/blogs/devops/aws-announces-workspace-context-awareness-for-amazon-q-developer-chat/

Today, Amazon Web Services (AWS) announced the release of workspace context awareness in Amazon Q Developer chat. By including @workspace in your prompt, Amazon Q Developer will automatically ingest and index all code files, configurations, and project structure, giving the chat comprehensive context across your entire application within the integrated development environment (IDE).

Throughout the software development lifecycle, developers, and IT professionals face challenges in understanding, creating, troubleshooting, and modernizing complex applications. Amazon Q Developer’s workspace context enhances its ability to address these issues by providing a comprehensive understanding of the entire codebase. During the planning phase, it enables gaining insights into the overall architecture, dependencies, and coding patterns, facilitating more complete and accurate responses and descriptions. When writing code, workspace awareness allows Amazon Q Developer to suggest code and solutions that require context from different areas without constant file switching. For troubleshooting, deeper contextual understanding aids in comprehending how various components interact, accelerating root cause analysis. By learning about the collection of files and folders in your workspace, Amazon Q Developer delivers accurate and relevant responses, tailored to the specific codebase, streamlining development efforts across the entire software lifecycle.

In this post, we’ll explore:

  • How @workspace works
  • How to use @workspace to:
    • Understand your projects and code
    • Navigate your project using natural language descriptions
    • Generate code and solutions that demonstrate workspace awareness
  • How to get started

Our goal is for you to gain a comprehensive understanding of how the @workspace context will increase developer productivity and accuracy of Amazon Q Developer responses.

How @workspace works

Amazon Q Developer chat now utilizes advanced machine learning in the client to provide a comprehensive understanding of your codebase within the integrated development environment (IDE).

The key processes are:

  • Local Workspace Indexing: When enabled, Amazon Q Developer will index programming files or configuration files in your project upon triggering with @workspace for the first time. Non-essential files like binaries and those specified in .gitignore are intelligently filtered out during this process, focusing only on relevant code assets. This indexing takes approximately 5–20 minutes for workspace sizes up to 200 MB.
  • Persisted and Auto-Refreshed Index: The created index is persisted to disk, allowing fast loading on subsequent openings of the same workspace. If the index is over 24 hours old, it is automatically refreshed by re-indexing all files.
  • Memory-Aware Indexing: To prevent resource overhead, indexing stops at either a hard limit on size or when available system memory reaches a minimum threshold.
  • Continuous Updates: After initial indexing, the index is incrementally updated whenever you finish editing files in the IDE by closing the file or moving to another tab.

By creating and maintaining a comprehensive index of your codebase, Amazon Q Developer is empowered with workspace context awareness, enabling rich, project-wide assistance tailored to your development needs. When responding to chat requests, instructions, and questions, Amazon Q Developer can now use its knowledge of the rest of the workspace to augment the context of the currently open files.

Let’s see how @workspace can help!

Customer Use-Cases

Onboarding and Knowledge Sharing

You can quickly get up to speed on implementation details by asking questions like What are the key classes with application logic in this @workspace?
Animation showing Amazon Q Developer chat being prompted for "What are the key classes with application logic in this @workspace?". Q Developer responds with listing of classes and folders that are considered important with an explanation.

You can ask other discovery questions about how code works: Does this application authenticate players prior to starting a game? @workspace
Animation of a chat conversation demonstrating the workspace context capability in Amazon Q Developer. The user asks '@workspace Does this application authenticate players prior to starting a game?'. Q Developer responds with a detailed explanation of the application's behavior, indicating that it does not perform player authentication before starting a game.

You can then follow up with documentation requests: Can you document, using markdown, the workflow in this @workspace to start a game?
Animation of a chat conversation using the workspace context capability in Amazon Q Developer. The user requests '@workspace Can you document using markdown the workflow to start a game?'. Q Developer responds with detailed markdown-formatted documentation outlining the steps and code involved in starting a game within the application.

Project-Wide Code Discovery and Understanding

You can understand how a function or class is used across the workspace by asking: How does this application validate the guessed word’s correctness? @workspace
Animation of a chat conversation using the workspace context capability in Amazon Q Developer. The user inquires 'How does this application validate the guessed word's correctness? @workspace '. Q Developer provides an explanation detailing the specific classes and functions involved in validating a player's word guess within the application.

You can then ask about how this is communicated to the player: @workspace How are the results of this validation rendered to the web page?
Animation of a chat conversation using the workspace context capability in Amazon Q Developer. The user asks '@workspace How are the results of this validation rendered to the web page?'. Q Developer explains the process of rendering the validation results on the web page, including identifying the specific code responsible for this functionality.

Code Generation with Multi-File Context

You can also generate tests, new features, or extend functionality while leveraging context from other project files with prompts like @workspace Find the class that generates the random words and create a unit test for it.
Animation of a chat conversation using the workspace context capability in Amazon Q Developer. The user requests '@workspace Find the class that generates the random words and create a unit test for it'.

Project-Wide Analysis and Remediation

Create data flow diagrams that require application workflow knowledge with @workspace Can you provide a UML diagram of the data flow between the front-end and the back-end? Using your built-in UML Previewer you can view the resulting diagram.
Animation of a chat conversation using the workspace context capability in Amazon Q Developer. The user requests '@workspace Can you provide a UML diagram of the dataflow between the front-end and the back-end?'.

With @workspace, Amazon Q Developer chat becomes deeply aware of workspace’s unique code, enabling efficient development, maintenance, and knowledge sharing.

Getting Started

Enabling the powerful workspace context capability in Amazon Q Developer chat is straightforward. Here’s how to get started:

  1. Open Your Project in the IDE: Launch your integrated development environment (IDE) and open the workspace or project you want the Amazon Q to understand.
  2. Start a New Chat Session: Start a new chat session within the Amazon Q Developer chat panel if not already open.
  3. “Enable” Workspace Context :To activate the project-wide context, simply include @workspace in the prompt. For example: How does the authentication flow work in this @workspace? When enabled, the first time Amazon Q Developer sees the @workspace keyword for the current workspace, Amazon Q Developer will ingest and analyze the code, configuration, and structure of the project.
    1. If not already enabled, Amazon Q Developer will instruct you to do so.
    2. Select the check the box for Amazon Q: Local Workspace IndexAnimation showing how to Amazon Q Developer chat will indicate when workspace context is enabled and how to enable in settings.
  4. Try Different Query Types: With @workspace context, you can ask a wide range of questions and provide instructions that leverage the full project context:
    1. Where is the business logic to handle users in this @workspace?
    2. @workspace Explain the data flow between the frontend and backend.
    3. Add new API tests using the existing test utilities found in the @workspace.
  5. Iterate and Refine: Try rephrasing your query or explicitly including more context by selecting code or mentioning specific files when the response doesn’t meet your expectations. The more relevant information you provide, the better Amazon Q Developer can understand your intent. For optimal results using workspace context, it’s recommended to use specific terminology present in your codebase, avoid overly broad queries, and leverage available examples, references, and code snippets to steer Amazon Q Developer effectively.

Conclusion

In this post we introduced Amazon Q Developer’s workspace awareness in chat via the @workspace keyword, highlighting the benefits of using workspace when understanding code, responding to questions, and generating new code. By allowing Amazon Q Developer to analyze and understand your project structure, workspace context unlocks new possibilities for development productivity gains.

If you are new to Amazon Q Developer, I highly recommend you check out Amazon Q Developer documentation and the Q-Words workshop.

About the author:

Will Matos

Will Matos is a Principal Specialist Solutions Architect at AWS, revolutionizing developer productivity through Generative AI, AI-powered chat interfaces, and code generation. With 25 years of tech experience, he collaborates with product teams to create intelligent solutions that streamline workflows and accelerate software development cycles. A thought leader engaging early adopters, Will bridges innovation and real-world needs.

Protein similarity search using ProtT5-XL-UniRef50 and Amazon OpenSearch Service

Post Syndicated from Camillo Anania original https://aws.amazon.com/blogs/big-data/protein-similarity-search-using-prott5-xl-uniref50-and-amazon-opensearch-service/

A protein is a sequence of amino acids that, when chained together, creates a 3D structure. This 3D structure allows the protein to bind to other structures within the body and initiate changes. This binding is core to the working of many drugs.

A common workflow within drug discovery is searching for similar proteins, because similar proteins likely have similar properties. Given an initial protein, researchers often look for variations that exhibit stronger binding, better solubility, or reduced toxicity. Despite advances in protein structure prediction, it’s still sometimes necessary to predict protein properties based on sequence alone. Thus, there is a need to quickly and at-scale get similar sequences based on an input sequence. In this blog post, we propose a solution based on Amazon OpenSearch Service for similarity search and the pretrained model ProtT5-XL-UniRef50, which we will use to generate embeddings. A repository providing such solution is available here. ProtT5-XL-UniRef50 is based on the t5-3b model and was pretrained on a large corpus of protein sequences in a self-supervised fashion.

Before diving into our solution, it’s important to understand what embeddings are and why they’re crucial for our task. Embeddings are dense vector representations of objects—proteins in our case—that capture the essence of their properties in a continuous vector space. An embedding is essentially a compact vector representation that encapsulates the significant features of an object, making it easier to process and analyze. Embeddings play an important role in understanding and processing complex data. They not only reduce dimensionality but also capture and encode intrinsic properties. This means that objects (such as words or proteins) with similar characteristics result in embeddings that are closer in the vector space. This proximity allows us to perform similarity searches efficiently, making embeddings invaluable for identifying relationships and patterns in large datasets.

Consider the analogy of fruits and their properties. In an embedding space, fruits such as mandarins and oranges would be close to each other because they share some characteristics, such as being round, color, and having similar nutritional properties. Similarly, bananas would be close to plantains, reflecting their shared properties. Through embeddings, we can understand and explore these relationships intuitively.

ProtT5-XL-UniRef50 is a machine learning (ML) model specifically designed to understand the language of proteins by converting protein sequences into multidimensional embeddings. These embeddings capture biological properties, allowing us to identify proteins with similar functions or structures in a multi-dimensional space because similar proteins will be encoded close together. This direct encoding of proteins into embeddings is crucial for our similarity search, providing a robust foundation for identifying potential drug targets or understanding protein functions.

Embeddings for the UniProtKB/Swiss-Prot protein database, which we use for this post, have been pre-computed and are available for download. If you have your own novel proteins, you can compute embeddings using ProtT5-XL-UniRef50, and then use these pre-computed embeddings to find known proteins with similar properties

In this post, we outline the broad functionalities of the solution and its components. Following this, we provide a brief explanation of what embeddings are, discussing the specific model used in our example. We then show how you can run this model on Amazon SageMaker. In addition, we dive into how to use the OpenSearch Service as a vector database. Finally, we demonstrate some practical examples of running similarity searches on protein sequences.

Solution overview

Let’s walk through the solution and all its components. Code for this solution is available on GitHub.

  1. We use OpenSearch Service vector database (DB) capabilities to store a sample of 20 thousand pre-calculated embeddings. These will be used to demonstrate similarity search. OpenSearch Service has advanced vector DB capabilities supporting multiple popular vector DB algorithms. For an overview of such capabilities see Amazon OpenSearch Service’s vector database capabilities explained.
  2. The open source prot_t5_xl_uniref50 ML model, hosted on Huggingface Hub, was used to calculate protein embeddings. We use the SageMaker Huggingface Inference Toolkit to quickly customize and deploy the model on SageMaker.
  3. The model is deployed and the solution is ready to calculate embeddings on any input protein sequence and perform similarity search against the protein embeddings we have preloaded on OpenSearch Service.
  4. We use a SageMaker Studio notebook to show how to deploy the model on SageMaker and then use an endpoint to extract protein features in the form of embeddings.
  5. After we have generated the embeddings in real time from the SageMaker endpoint, we run a query on OpenSearch Service to determine the five most similar proteins currently stored on OpenSearch Service index.
  6. Finally, the user can see the result directly from the SageMaker Studio notebook.
  7. To understand if the similarity search works well, we choose the Immunoglobulin Heavy Diversity 2/OR15-2A protein and we calculate its embeddings. The embeddings returned by the model are pre-residue, which is a detailed level of analysis where each individual residue (amino acid) in the protein is considered. In our case, we want to focus on the overall structure, function, and properties of the protein, so we calculate the per-protein embeddings. We achieve that by doing dimensionality reduction, calculating the mean overall per-residue features. Finally, we use the resulting embeddings to perform a similarity search and the first five proteins ordered by similarity are:
    • Immunoglobulin Heavy Diversity 3/OR15-3A
    • T Cell Receptor Gamma Joining 2
    • T Cell Receptor Alpha Joining 1
    • T Cell Receptor Alpha Joining 11
    • T Cell Receptor Alpha Joining 50

These are all immune cells with T cell receptors being a subtype of immunoglobulin. The similarity surfaced proteins that are all bio-functionally similar.

Costs and clean up

The solution we just walked through creates an OpenSearch Service domain which is billed according to number and instance type selected during creation time, see the OpenSearch Service Pricing page for the rate of those. You will also be charged for the SageMaker endpoint created by the deploy-and-similarity-search notebook, which is currently using a ml.g4dn.8xlarge instance type. See SageMaker pricing for details.

Finally, you are charged for the SageMaker Studio Notebooks according to the instance type you are using as detailed on the pricing page.

To clean up the resources created by this solution:

Conclusion

In this blog post we described a solution capable of calculating protein embeddings and performing similarity searches to find similar proteins. The solution uses the open source ProtT5-XL-UniRef50 model to calculate the embeddings and it deploys it on SageMaker Inference. We used OpenSearch Service as the vector DB. OpenSearch Service is pre-populated with 20 thousand human proteins from UniProt. Finally, the solution was validated by performing a similarity search on the Immunoglobulin Heavy Diversity 2/OR15-2A protein. We successfully evaluated that the proteins returned from OpenSearch Service are all in the immunoglobulin family and are bio-functionally similar. Code for this solution is available in GitHub.

The solution can be further tuned by testing different supported OpenSearch Service KNN algorithms and scaled by importing additional protein embeddings into OpenSearch Service indexes.

Resources:

  • Elnaggar A, et al. “ProtTrans: Toward Understanding the Language of Life Through Self-Supervised Learning”. IEEE Trans Pattern Anal Mach Intell. 2020.
  • Mikolov, T.; Yih, W.; Zweig, G. “Linguistic Regularities in Continuous Space Word Representations”. HLT-Naacl: 746–751. 2013.

About the Authors

that's meCamillo Anania is a Senior Solutions Architect at AWS. He is a tech enthusiast who loves helping healthcare and life science startups get the most out of the cloud. With a knack for cloud technologies, he’s all about making sure these startups can thrive and grow by leveraging the best cloud solutions. He is excited about the new wave of use cases and possibilities unlocked by GenAI and does not miss a chance to dive into them.

Adam McCarthy is the EMEA Tech Leader for Healthcare and Life Sciences Startups at AWS. He has over 15 years’ experience researching and implementing machine learning, HPC, and scientific computing environments, especially in academia, hospitals, and drug discovery.

Vector search for Amazon MemoryDB is now generally available

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/vector-search-for-amazon-memorydb-is-now-generally-available/

Today, we are announcing the general availability of vector search for Amazon MemoryDB, a new capability that you can use to store, index, retrieve, and search vectors to develop real-time machine learning (ML) and generative artificial intelligence (generative AI) applications with in-memory performance and multi-AZ durability.

With this launch, Amazon MemoryDB delivers the fastest vector search performance at the highest recall rates among popular vector databases on Amazon Web Services (AWS). You no longer have to make trade-offs around throughput, recall, and latency, which are traditionally in tension with one another.

You can now use one MemoryDB database to store your application data and millions of vectors with single-digit millisecond query and update response times at the highest levels of recall. This simplifies your generative AI application architecture while delivering peak performance and reducing licensing cost, operational burden, and time to deliver insights on your data.

With vector search for Amazon MemoryDB, you can use the existing MemoryDB API to implement generative AI use cases such as Retrieval Augmented Generation (RAG), anomaly (fraud) detection, document retrieval, and real-time recommendation engines. You can also generate vector embeddings using artificial intelligence and machine learning (AI/ML) services like Amazon Bedrock and Amazon SageMaker and store them within MemoryDB.

Which use cases would benefit most from vector search for MemoryDB?
You can use vector search for MemoryDB for the following specific use cases:

1. Real-time semantic search for retrieval-augmented generation (RAG)
You can use vector search to retrieve relevant passages from a large corpus of data to augment a large language model (LLM). This is done by taking your document corpus, chunking them into discrete buckets of texts, and generating vector embeddings for each chunk with embedding models such as the Amazon Titan Multimodal Embeddings G1 model, then loading these vector embeddings into Amazon MemoryDB.

With RAG and MemoryDB, you can build real-time generative AI applications to find similar products or content by representing items as vectors, or you can search documents by representing text documents as dense vectors that capture semantic meaning.

2. Low latency durable semantic caching
Semantic caching is a process to reduce computational costs by storing previous results from the foundation model (FM) in-memory. You can store prior inferenced answers alongside the vector representation of the question in MemoryDB and reuse them instead of inferencing another answer from the LLM.

If a user’s query is semantically similar based on a defined similarity score to a prior question, MemoryDB will return the answer to the prior question. This use case will allow your generative AI application to respond faster with lower costs from making a new request to the FM and provide a faster user experience for your customers.

3. Real-time anomaly (fraud) detection
You can use vector search for anomaly (fraud) detection to supplement your rule-based and batch ML processes by storing transactional data represented by vectors, alongside metadata representing whether those transactions were identified as fraudulent or valid.

The machine learning processes can detect users’ fraudulent transactions when the net new transactions have a high similarity to vectors representing fraudulent transactions. With vector search for MemoryDB, you can detect fraud by modeling fraudulent transactions based on your batch ML models, then loading normal and fraudulent transactions into MemoryDB to generate their vector representations through statistical decomposition techniques such as principal component analysis (PCA).

As inbound transactions flow through your front-end application, you can run a vector search against MemoryDB by generating the transaction’s vector representation through PCA, and if the transaction is highly similar to a past detected fraudulent transaction, you can reject the transaction within single-digit milliseconds to minimize the risk of fraud.

Getting started with vector search for Amazon MemoryDB
Look at how to implement a simple semantic search application using vector search for MemoryDB.

Step 1. Create a cluster to support vector search
You can create a MemoryDB cluster to enable vector search within the MemoryDB console. Choose Enable vector search in the Cluster settings when you create or update a cluster. Vector search is available for MemoryDB version 7.1 and a single shard configuration.

Step 2. Create vector embeddings using the Amazon Titan Embeddings model
You can use Amazon Titan Text Embeddings or other embedding models to create vector embeddings, which is available in Amazon Bedrock. You can load your PDF file, split the text into chunks, and get vector data using a single API with LangChain libraries integrated with AWS services.

import redis
import numpy as np
from langchain.document_loaders import PyPDFLoader
from langchain.text_splitter import RecursiveCharacterTextSplitter
from langchain.embeddings import BedrockEmbeddings

# Load a PDF file and split document
loader = PyPDFLoader(file_path=pdf_path)
        pages = loader.load_and_split()
        text_splitter = RecursiveCharacterTextSplitter(
            separators=["\n\n", "\n", ".", " "],
            chunk_size=1000,
            chunk_overlap=200,
        )
        chunks = loader.load_and_split(text_splitter)

# Create MemoryDB vector store the chunks and embedding details
client = RedisCluster(
        host=' mycluster.memorydb.us-east-1.amazonaws.com',
        port=6379,
        ssl=True,
        ssl_cert_reqs="none",
        decode_responses=True,
    )

embedding =  BedrockEmbeddings (
           region_name="us-east-1",
 endpoint_url=" https://bedrock-runtime.us-east-1.amazonaws.com",
    )

#Save embedding and metadata using hset into your MemoryDB cluster
for id, dd in enumerate(chucks*):
     y = embeddings.embed_documents([dd])
     j = np.array(y, dtype=np.float32).tobytes()
     client.hset(f'oakDoc:{id}', mapping={'embed': j, 'text': chunks[id] } )

Once you generate the vector embeddings using the Amazon Titan Text Embeddings model, you can connect to your MemoryDB cluster and save these embeddings using the MemoryDB HSET command.

Step 3. Create a vector index
To query your vector data, create a vector index using theFT.CREATE command. Vector indexes are also constructed and maintained over a subset of the MemoryDB keyspace. Vectors can be saved in JSON or HASH data types, and any modifications to the vector data are automatically updated in a keyspace of the vector index.

from redis.commands.search.field import TextField, VectorField

index = client.ft(idx:testIndex).create_index([
        VectorField(
            "embed",
            "FLAT",
            {
                "TYPE": "FLOAT32",
                "DIM": 1536,
                "DISTANCE_METRIC": "COSINE",
            }
        ),
        TextField("text")
        ]
    )

In MemoryDB, you can use four types of fields: numbers fields, tag fields, text fields, and vector fields. Vector fields support K-nearest neighbor searching (KNN) of fixed-sized vectors using the flat search (FLAT) and hierarchical navigable small worlds (HNSW) algorithm. The feature supports various distance metrics, such as euclidean, cosine, and inner product. We will use the euclidean distance, a measure of the angle distance between two points in vector space. The smaller the euclidean distance, the closer the vectors are to each other.

Step 4. Search the vector space
You can use FT.SEARCH and FT.AGGREGATE commands to query your vector data. Each operator uses one field in the index to identify a subset of the keys in the index. You can query and find filtered results by the distance between a vector field in MemoryDB and a query vector based on some predefined threshold (RADIUS).

from redis.commands.search.query import Query

# Query vector data
query = (
    Query("@vector:[VECTOR_RANGE $radius $vec]=>{$YIELD_DISTANCE_AS: score}")
     .paging(0, 3)
     .sort_by("vector score")
     .return_fields("id", "score")     
     .dialect(2)
)

# Find all vectors within 0.8 of the query vector
query_params = {
    "radius": 0.8,
    "vec": np.random.rand(VECTOR_DIMENSIONS).astype(np.float32).tobytes()
}

results = client.ft(index).search(query, query_params).docs

For example, when using cosine similarity, the RADIUS value ranges from 0 to 1, where a value closer to 1 means finding vectors more similar to the search center.

Here is an example result to find all vectors within 0.8 of the query vector.

[Document {'id': 'doc:a', 'payload': None, 'score': '0.243115246296'},
 Document {'id': 'doc:c', 'payload': None, 'score': '0.24981123209'},
 Document {'id': 'doc:b', 'payload': None, 'score': '0.251443207264'}]

To learn more, you can look at a sample generative AI application using RAG with MemoryDB as a vector store.

What’s new at GA
At re:Invent 2023, we released vector search for MemoryDB in preview. Based on customers’ feedback, here are the new features and improvements now available:

  • VECTOR_RANGE to allow MemoryDB to operate as a low latency durable semantic cache, enabling cost optimization and performance improvements for your generative AI applications.
  • SCORE to better filter on similarity when conducting vector search.
  • Shared memory to not duplicate vectors in memory. Vectors are stored within the MemoryDB keyspace and pointers to the vectors are stored in the vector index.
  • Performance improvements at high filtering rates to power the most performance-intensive generative AI applications.

Now available
Vector search is available in all Regions that MemoryDB is currently available. Learn more about vector search for Amazon MemoryDB in the AWS documentation.

Give it a try in the MemoryDB console and send feedback to the AWS re:Post for Amazon MemoryDB or through your usual AWS Support contacts.

— Channy

Build enterprise-grade applications with natural language using AWS App Studio (preview)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/build-custom-business-applications-without-cloud-expertise-using-aws-app-studio-preview/

Organizations often struggle to solve their business problems in areas like claims processing, inventory tracking, and project approvals. Custom business applications could provide a solution to solve these problems and help an organization work more effectively but have historically required a professional development team to build and maintain. But often, development capacity is unavailable or too expensive, leaving businesses using inefficient tools and processes.

Today, we’re announcing a public preview of AWS App Studio. App Studio is a generative artificial intelligence (AI)-powered service that uses natural language to create enterprise-grade applications in minutes, without requiring software development skills.

Here’s a quick look at what App Studio can do. Once I’m signed in to App Studio, I select CREATE A NEW APP using the generative AI assistant. I describe that I need a project approval app. App Studio then generates an app for me, complete with a user interface, data models, and business logic. The entire app generation process is complete in minutes. 

Note: This animation above shows the flow at an accelerated speed for demonstration purposes.

While writing this post, I discovered that App Studio is useful for various technical professionals. IT project managers, data engineers, and enterprise architects can use it to create and manage secure business applications in minutes instead of days. App Studio helps organizations build end-to-end custom applications, and it has two main user roles:

  • Admin – Members in this group can manage groups and roles, create and edit connectors, and maintain visibility into other apps built within their organization. In addition to these permissions, admins can also build apps of their own. To enable and set up App Studio or to learn more about what you can do as an administrator, you can jump to the Getting started with AWS App Studio (preview) section.
  • Builder – Members of the builder group can create, build, and share applications. If you’re more interested in the journey of building applications, you can skip to the Using App Studio as a builder: Creating an application section.

Getting started with AWS App Studio
AWS App Studio integrates with AWS IAM Identity Center, making it easier for me to secure access with the flexibility to integrate with existing single sign-on (SSO) and integration with Lightweight Directory Access Protocol (LDAP). Also, App Studio manages the application deployments and operations, removing the time and effort required to operate applications. Now, I can spend more of my time adding features to an application and customizing it to user needs.

Before I can use App Studio to create my applications, I need to enable the service. Here is how an administrator would set up an App Studio instance.

First, I need to go to the App Studio management console and choose Get started.

As mentioned, App Studio integrates with IAM Identity Center and will automatically detect if you have an existing organization instance in IAM Identity Center. To learn more about the difference between an organization and an account instance on IDC, you can visit the Manage organization and account instances of IAM Identity Center page.

In this case, I don’t have any organization instance, so App Studio will guide me through creating an account instance in IAM Identity Center. Here, as an administrator, I select Create an account instance for me. 

In the next section, Create users and groups and add them to App Studio, I need to define both an admin and builder group. In this section, I add myself as the admin, and I’ll add users into the builder group later. 

The last part of the onboarding process is to review and check the tick box in the Acknowledgment section, then select Set up.

When the onboarding process is complete, I can see from the Account page that my App Studio is Active and ready to use. At this point, I have a unique App Studio instance URL that I can access.

This onboarding scenario illustrates how you can start without an instance preconfigured in IAM Identity Center . Learn more on the Creating and setting up an App Studio instance for the first time page to understand how to use your existing IAM Identity Center instance. 

Because App Studio created the AWS IAM Identity Center account instance for me, I received an email along with instructions to sign in to App Studio. Once I select the link, I’ll need to create a password for my account and define the multi-factor authentication (MFA) to improve the security posture of my account.

Then, I can sign in to App Studio.

Add additional users (optional)
App Studio uses AWS IAM Identity Center to manage users and groups. This means that if I need to invite additional users into my App Studio instance, I need to do that in IAM Identity Center. 

For example, here’s the list of my users. I can add more users by selecting Add user. Once I’ve finished adding users, they will receive an email with the instructions to activate their accounts.

If I need to create additional groups, I can do so by selecting Create group on the Groups page. The following screenshot shows groups I’ve defined for my account instance in IAM Identity Center.

Using AWS App Studio as an administrator
Now, I’m switching to the App Studio and signing in as an administrator. Here, I can see two main sections: Admin hub and Builder hub.

As an administrator, I can grant users access to App Studio by associating existing user groups with roles in the Roles section:

To map the group I created in my IAM Identity Center, I select Add group and select the Group identifier and Role. There are three roles I can configure: admin, builder, and app user. To understand the difference between each role, visit the Managing access and roles in App Studio page.

As an administrator, I can incorporate various data sources with App Studio using connectors. App Studio provides built-in connectors to integrate with AWS services such as Amazon Aurora, Amazon DynamoDB, and Amazon Simple Storage Service (Amazon S3). It also has a built-in connector for Salesforce and a generic API and OpenAPI connector to integrate with third-party services.

Furthermore, App Studio automatically created a managed DynamoDB connector for me to get started. I also have the flexibility to create additional connectors by selecting Create connector. 

On this page, I can create other connectors to AWS services. If I need other AWS services, I can select Other AWS services. To learn how to define your IAM role for your connectors, visit Connect App Studio to other services with connectors.

Using App Studio as a builder: Creating an application
As a builder, I can use the App Studio generative AI–powered low-code building environment to create secure applications. To start, I can describe the application that I need in natural language, such as “Build an application to review and process invoices.” Then, App Studio will generate the application, complete with the data models, business logic, and a multipage UI.

Here’s where the fun begins. It’s time for me to build apps in App Studio. On the Builder hub page, I select Create app.

I give it a name, and there are two options for me to build the app: Generate an app with AI or Start from scratch. I select Generate an app with AI. 

On the next page, I can start building the app by simply describing what I need in the text box. I also can choose sample prompts which are available on the right panel. 

Then, App Studio will prepare app requirements for me. I can improve my plan for the application by refining the prompt and reviewing the updated requirements. Once I’m happy with the results, I select Generate app, and App Studio will generate an application for me.

I found this to be a good experience for me when I started building apps with App Studio. The generative AI capability built into App Studio generated an app for me in minutes, compared to the hours or even days it would have taken me to get to the same point using other tools.

After a few minutes, my app is ready. I also see that App Studio prepares a quick tutorial for me to navigate around and understand different areas. 

There are three main areas in App Studio: Pages, Automations, and Data. I always like to start building my apps by defining the data models first, so let’s navigate to the Data section.

In the Data section, I can model my application data with the managed data store powered by DynamoDB or using the available data connectors. Because I chose to let AI generate this app, I have all the data entities defined for me. If I opted to do it manually, I would need to create entities representing the different data tables and field types for my application.

Once I’m happy with the data entities, I can build visual pages. In this area, I can create the UI for my users. I can add and arrange components like tables, forms, and buttons to create a tailored experience for my end users.

While I’m building the app, I can see the live preview by selecting Preview. This is useful for testing the layout and functionality of my application.

But the highlight for me in these three areas is the Automations. With the automations, I can define rules, workflows, and any actions that define or extend my application’s business logic. Because I chose to build this application with App Studio’s generative AI assistant, it automatically created and wired up multiple different automations needed for my application.

For example, every time a new project is submitted, it will trigger an action to create a project and send a notification email. 

I can also extend my business logic by invoking API callouts, AWS Lambda, or other AWS services. Besides creating the project, I’d also like to archive the project in a flat-file format into an S3 bucket. To do that, I also need to do some processing, and I happen to already have the functionality built in an existing Lambda function.

Here, I select Invoke Lambda, as shown in the previous screenshot. Then, I need to set the Connector, Function name, and the Function event payload to pass into my existing Lambda function.

Finally, after I’m happy with all the UI pages, data entities, and automations, I can publish it by selecting Publish. I have the flexibility to publish my app in a Testing or Production environment. This helps me to test my application before pushing it to production.

Join the preview
AWS App Studio is currently in preview, and you can access it in the US West (Oregon) AWS Region, but your applications can connect to your data in other AWS Regions.

Build secure, scalable, and performant custom business applications to modernize and streamline mission-critical tasks with AWS App Studio. Learn more about all the features and functionalities on the AWS App Studio documentation page, and join the conversation in the #aws-app-studio channel in the AWS Developers Slack workspace.

Happy building,

— Donnie

Amazon Q Apps, now generally available, enables users to build their own generative AI apps

Post Syndicated from Prasad Rao original https://aws.amazon.com/blogs/aws/amazon-q-apps-now-generally-available-enables-users-to-build-their-own-generative-ai-apps/

When we launched Amazon Q Business in April 2024, we also previewed Amazon Q Apps. Amazon Q Apps is a capability within Amazon Q Business for users to create generative artificial intelligence (generative AI)–powered apps based on the organization’s data. Users can build apps using natural language and securely publish them to the organization’s app library for everyone to use.

After collecting your feedback and suggestions during the preview, today we’re making Amazon Q Apps generally available. We’re also adding some new capabilities that were not available during the preview, such as API for Amazon Q Apps and the ability to specify data sources at the individual card level.

I’ll expand on the new features in a moment, but let’s first look into how to get started with Amazon Q Apps.

Transform conversations into reusable apps
Amazon Q Apps allows users to generate an app from their conversation with Amazon Q Business. Amazon Q Apps intelligently captures the context of conversation to generate an app tailored to specific needs. Let’s see it in action!

As I started writing this post, I thought of getting help from Amazon Q Business to generate a product overview of Amazon Q Apps. After all, Amazon Q Business is for boosting workforce productivity. So, I uploaded the product messaging documents to an Amazon Simple Storage Service (Amazon S3) bucket and added it as a data source using Amazon S3 connector for Amazon Q Business.

I start my conversation with the prompt:

I’m writing a launch post for Amazon Q Apps.
Here is a short description of the product: Employees can create lightweight, purpose-built Amazon Q Apps within their broader Amazon Q Business application environment.
Generate an overview of the product and list its key features.

Amazon Q Business Chat

After starting the conversation, I realize that creating a product overview given a product description would also be useful for others in the organization. I choose Create Amazon Q App to create a reusable and shareable app.

Amazon Q Business automatically generates a prompt to create an Amazon Q App and displays the prompt to me to verify and edit if need be:

Build an app that takes in a short text description of a product or service, and outputs an overview of that product/service and a list of its key features, utilizing data about the product/service known to Q.

Amazon Q Apps Creator

I choose Generate to continue the creation of the app. It creates a Product Overview Generator app with four cards—two input cards to get user inputs and two output cards that display the product overview and its key features.

Product Overview Generator App

I can adjust the layout of the app by resizing the cards and moving them around.

Also, the prompts for the individual text output cards are automatically generated so I can view and edit them. I choose the edit icon of the Product Overview card to see the prompt in the side panel.

In the side panel, I can also select the source for the text output card to generate the output using either large language model (LLM) knowledge or approved data sources. For the approved data sources, I can select one or more data sources that are configured for this Amazon Q Business application. I select the Marketing (Amazon S3) data source I had configured for creating this app.

Edit Text Output Card Prompt and select source

As you would notice, I generated a fully functional app from the conversation itself without having to make any changes to the base prompt or the individual text output card prompts.

I can now publish this app to the organization’s app library by choosing Publish. But before publishing the app, let’s look at another way to create Amazon Q apps.

Create generative AI apps using natural language
Instead of using conversation in Amazon Q Business as a starting point to create an app, I can choose Apps and use my own words to describe the app I want to create. Or I can try out the prompts from one of the preconfigured examples.

Amazon Q App

I can enter the prompt to fit the purpose and choose Generate to create the app.

Share apps with your team
Once you’re happy with both layouts and prompts, and are ready to share the app, you can publish the app to a centralized app library to give access to all users of this Amazon Q Business application environment.

Amazon Q Apps inherits the robust security and governance controls from Amazon Q Business, ensuring that data sources, user permissions, and guardrails are maintained. So, when other users run the app, they only see responses based on data they have access to in the underlying data sources.

For the Product Overview Generator app I created, I choose Publish. It displays the preview of the app and provides an option to select up to three labels. Labels help classify the apps by departments in the organization or any other categories. After selecting the labels, I choose Publish again on the preview popup.

Publish Amazon Q App

The app will instantly be available in the Amazon Q Apps library for others to use, copy, and build on top of. I choose Library to browse the Amazon Q Apps Library and find my Product Overview Generator app.

Amazon Q Apps Library

Customize apps in the app library for your specific needs
Amazon Q Apps allows users to quickly scale their individual or team productivity by customizing and tailoring shared apps to their specific needs. Instead of starting from scratch, users can review existing apps, use them as-is, or modify them and publish their own versions to the app library.

Let’s browse the app library and find an app to customize. I choose the label General to find apps in that category.

Document Editing Assistant App

I see a Document Editing Assistant app that reviews documents to correct grammatical mistakes. I would like to create a new version of the app to include a document summary too. Let’s see how we can do it.

I choose Open, and it opens the app with an option to Customize.

Open Document Editing Assistant App

I choose Customize, and it creates a copy of the app for me to modify it.

Customize App

I update the Title and Description of the app by choosing the edit icon of the app title.

I can see the original App Prompt that was used to generate this app. I can copy the prompt and use it as the starting point to create a similar app by updating it to include a description of the functionality that I would like to add and have Amazon Q Apps Creator take care of it. Or I can continue modifying this copy of the app.

There is an option to edit or delete existing cards. For example, I can edit the prompt of the Edited Document text output card by choosing the edit icon of the card.

Edit Text Output Card Prompt

To add more features, you can add more cards, such as a user input, text output, file upload, or preconfigured plugin by your administrator. The file upload card, for example, can be used to provide a file as another data source to refine or fine-tune the answers to your questions. The plugin card can be used, for example, to create a Jira ticket for any action item that needs to be performed as a follow-up.

I choose Text output to add a new card that will summarize the document. I enter the title as Document Summary and prompt as follows:

Summarize the key points in @Upload Document in a couple of sentences

Add Text Output Card

Now, I can publish this customized app as a new app and share it with everyone in the organization.

What did we add after the preview?

As I mentioned, we have used your feedback and suggestions during the preview period to add new capabilities. Here are the new features we have added:

Specify data sources at card level – As I have shown while creating the app, you can specify data sources you would like the output to be generated from. We added this feature to improve the accuracy of the responses.

Your Amazon Q business instance can have multiple data sources configured. However, to create an app, you might need only a subset of these data sources, based on the use case. So now you can choose specific data sources for each of the text output cards in your app. Or if your usecase requires, you can configure the text output cards to use LLM knowledge instead of using any data sources.

Amazon Q Apps API – You can now create and manage Amazon Q Apps programmatically with APIs for managing apps, app library and app sessions. This allows you to integrate all the functionalities of Amazon Q Apps into the tools and applications of your choice.

Things to know:

  • Regions – Amazon Q Apps is generally available today in the Regions where Amazon Q Business is available, which are the US East (N. Virginia) and US West (Oregon) Regions.
  • Pricing – Amazon Q Apps is available with the Amazon Business Pro subscription ($20 per user per month), which gives users access to all the features of Amazon Q Business.
  • Learning resources – To learn more, visit Amazon Q Apps in the Amazon Q Business User Guide.

–  Prasad

Agents for Amazon Bedrock now support memory retention and code interpretation (preview)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/agents-for-amazon-bedrock-now-support-memory-retention-and-code-interpretation-preview/

With Agents for Amazon Bedrock, generative artificial intelligence (AI) applications can run multistep tasks across different systems and data sources. A couple of months back, we simplified the creation and configuration of agents. Today, we are introducing in preview two new fully managed capabilities:

Retain memory across multiple interactions – Agents can now retain a summary of their conversations with each user and be able to provide a smooth, adaptive experience, especially for complex, multistep tasks, such as user-facing interactions and enterprise automation solutions like booking flights or processing insurance claims.

Support for code interpretation – Agents can now dynamically generate and run code snippets within a secure, sandboxed environment and be able to address complex use cases such as data analysis, data visualization, text processing, solving equations, and optimization problems. To make it easier to use this feature, we also added the ability to upload documents directly to an agent.

Let’s see how these new capabilities work in more detail.

Memory retention across multiple interactions
With memory retention, you can build agents that learn and adapt to each user’s unique needs and preferences over time. By maintaining a persistent memory, agents can pick up right where the users left off, providing a smooth flow of conversations and workflows, especially for complex, multistep tasks.

Imagine a user booking a flight. Thanks to the ability to retain memory, the agent can learn their travel preferences and use that knowledge to streamline subsequent booking requests, creating a personalized and efficient experience. For example, it can automatically propose the right seat to a user or a meal similar to their previous choices.

Using memory retention to be more context-aware also simplifies business process automation. For example, an agent used by an enterprise to process customer feedback can now be aware of previous and on-going interactions with the same customer without having to handle custom integrations.

Each user’s conversation history and context are securely stored under a unique memory identifier (ID), ensuring complete separation between users. With memory retention, it’s easier to build agents that provide seamless, adaptive, and personalized experiences that continuously improve over time. Let’s see how this works in practice.

Using memory retention in Agents for Amazon Bedrock
In the Amazon Bedrock console, I choose Agents from the Builder Tools section of the navigation pane and start creating an agent.

For the agent, I use agent-book-flight as the name with this as description:

Help book a flight.

Then, in the agent builder, I select the Anthropic’s Claude 3 Sonnet model and enter these instructions:

To book a flight, you should know the origin and destination airports and the day and time the flight takes off.

In Additional settings, I enable User input to allow the agent to ask clarifying questions to capture necessary inputs. This will help when a request to book a flight misses some necessary information such as the origin and destination or the date and time of the flight.

In the new Memory section, I enable memory to generate and store a session summary at the end of each session and use the default 30 days for memory duration.

Console screenshot.

Then, I add an action group to search and book flights. I use search-and-book-flights as name and this description:

Search for flights between two destinations on a given day and book a specific flight.

Then, I choose to define the action group with function details and then to create a new Lambda function. The Lambda function will implement the business logic for all the functions in this action group.

I add two functions to this action group: one to search for flights and another to book flights.

The first function is search-for-flights and has this description:

Search for flights on a given date between two destinations.

All parameters of this function are required and of type string. Here are the parameters’ names and descriptions:

origin_airport – Origin IATA airport code
destination_airport –
Destination IATA airport code
date –
Date of the flight in YYYYMMDD format

The second function is book-flight and uses this description:

Book a flight at a given date and time between two destinations.

Again, all parameters are required and of type string. These are the names and descriptions for the parameters:

origin_airport – Origin IATA airport code
destination_airport – Destination IATA airport code
date – Date of the flight in YYYYMMDD format
time – Time of the flight in HHMM format

To complete the creation of the agent, I choose Create.

To access the source code of the Lambda function, I choose the search-and-book-flights action group and then View (near the Select Lambda function settings). Normally, I’d use this Lambda function to integrate with an existing system such as a travel booking platform. In this case, I use this code to simulate a booking platform for the agent.

import json
import random
from datetime import datetime, time, timedelta


def convert_params_to_dict(params_list):
    params_dict = {}
    for param in params_list:
        name = param.get("name")
        value = param.get("value")
        if name is not None:
            params_dict[name] = value
    return params_dict


def generate_random_times(date_str, num_flights, min_hours, max_hours):
    # Set seed based on input date
    seed = int(date_str)
    random.seed(seed)

    # Convert min_hours and max_hours to minutes
    min_minutes = min_hours * 60
    max_minutes = max_hours * 60

    # Generate random times
    random_times = set()
    while len(random_times) < num_flights:
        minutes = random.randint(min_minutes, max_minutes)
        hours, mins = divmod(minutes, 60)
        time_str = f"{hours:02d}{mins:02d}"
        random_times.add(time_str)

    return sorted(random_times)


def get_flights_for_date(date):
    num_flights = random.randint(1, 6) # Between 1 and 6 flights per day
    min_hours = 6 # 6am
    max_hours = 22 # 10pm
    flight_times = generate_random_times(date, num_flights, min_hours, max_hours)
    return flight_times
    
    
def get_days_between(start_date, end_date):
    # Convert string dates to datetime objects
    start = datetime.strptime(start_date, "%Y%m%d")
    end = datetime.strptime(end_date, "%Y%m%d")
    
    # Calculate the number of days between the dates
    delta = end - start
    
    # Generate a list of all dates between start and end (inclusive)
    date_list = [start + timedelta(days=i) for i in range(delta.days + 1)]
    
    # Convert datetime objects back to "YYYYMMDD" string format
    return [date.strftime("%Y%m%d") for date in date_list]


def lambda_handler(event, context):
    print(event)
    agent = event['agent']
    actionGroup = event['actionGroup']
    function = event['function']
    param = convert_params_to_dict(event.get('parameters', []))

    if actionGroup == 'search-and-book-flights':
        if function == 'search-for-flights':
            flight_times = get_flights_for_date(param['date'])
            body = f"On {param['date']} (YYYYMMDD), these are the flights from {param['origin_airport']} to {param['destination_airport']}:\n{json.dumps(flight_times)}"
        elif function == 'book-flight':
            body = f"Flight from {param['origin_airport']} to {param['destination_airport']} on {param['date']} (YYYYMMDD) at {param['time']} (HHMM) booked and confirmed."
        elif function == 'get-flights-in-date-range':
            days = get_days_between(param['start_date'], param['end_date'])
            flights = {}
            for day in days:
                flights[day] = get_flights_for_date(day)
            body = f"These are the times (HHMM) for all the flights from {param['origin_airport']} to {param['destination_airport']} between {param['start_date']} (YYYYMMDD) and {param['end_date']} (YYYYMMDD) in JSON format:\n{json.dumps(flights)}"
        else:
            body = f"Unknown function {function} for action group {actionGroup}."
    else:
        body = f"Unknown action group {actionGroup}."
    
    # Format the output as expected by the agent
    responseBody =  {
        "TEXT": {
            "body": body
        }
    }

    action_response = {
        'actionGroup': actionGroup,
        'function': function,
        'functionResponse': {
            'responseBody': responseBody
        }

    }

    function_response = {'response': action_response, 'messageVersion': event['messageVersion']}
    print(f"Response: {function_response}")

    return function_response

I prepare the agent to test it in the console and ask this question:

Which flights are available from London Heathrow to Rome Fiumicino on July 20th, 2024?

The agent replies with a list of times. I choose Show trace to get more information about how the agent processed my instructions.

In the Trace tab, I explore the trace steps to understand the chain of thought used by the agent’s orchestration. For example, here I see that the agent handled the conversion of the airport names to codes (LHR for London Heathrow, FCO for Rome Fiumicino) before calling the Lambda function.

In the new Memory tab, I see what’s the content of the memory. The console uses a specific test memory ID. In an application, to keep memory separated for each user, I can use a different memory ID for every user.

I look at the list of flights and ask to book one:

Book the one at 6:02pm.

The agent replies confirming the booking.

After a few minutes, after the session has expired, I see a summary of my conversation in the Memory tab.

Console screenshot.

I choose the broom icon to start with a new conversation and ask a question that, by itself, doesn’t provide a full context to the agent:

Which other flights are available on the day of my flight?

The agent recalls the flight that I booked from our previous conversation. To provide me with an answer, the agent asks me to confirm the flight details. Note that the Lambda function is just a simulation and didn’t store the booking information in any database. The flight details were retrieved from the agent’s memory.

Console screenshot.

I confirm those values and get the list of the other flights with the same origin and destination on that day.

Yes, please.

To better demonstrate the benefits of memory retention, let’s call the agent using the AWS SDK for Python (Boto3). To do so, I first need to create an agent alias and version. I write down the agent ID and the alias ID because they are required when invoking the agent.

In the agent invocation, I add the new memoryId option to use memory. By including this option, I get two benefits:

  • The memory retained for that memoryId (if any) is used by the agent to improve its response.
  • A summary of the conversation for the current session is retained for that memoryId so that it can be used in another session.

Using an AWS SDK, I can also get the content or delete the content of the memory for a specific memoryId.

import random
import string
import boto3
import json

DEBUG = False # Enable debug to see all trace steps
DATE_FORMAT = "%Y-%m-%d %H:%M:%S"

AGENT_ID = 'URSVOGLFNX'
AGENT_ALIAS_ID = 'JHLX9ERCMD'

SESSION_ID_LENGTH = 10
SESSION_ID = "".join(
    random.choices(string.ascii_uppercase + string.digits, k=SESSION_ID_LENGTH)
)

# A unique identifier for each user
MEMORY_ID = 'danilop-92f79781-a3f3-4192-8de6-890b67c63d8b' 
bedrock_agent_runtime = boto3.client('bedrock-agent-runtime', region_name='us-east-1')


def invoke_agent(prompt, end_session=False):
    response = bedrock_agent_runtime.invoke_agent(
        agentId=AGENT_ID,
        agentAliasId=AGENT_ALIAS_ID,
        sessionId=SESSION_ID,
        inputText=prompt,
        memoryId=MEMORY_ID,
        enableTrace=DEBUG,
        endSession=end_session,
    )

    completion = ""

    for event in response.get('completion'):
        if DEBUG:
            print(event)
        if 'chunk' in event:
            chunk = event['chunk']
            completion += chunk['bytes'].decode()

    return completion


def delete_memory():
    try:
        response = bedrock_agent_runtime.delete_agent_memory(
            agentId=AGENT_ID,
            agentAliasId=AGENT_ALIAS_ID,
            memoryId=MEMORY_ID,
        )
    except Exception as e:
        print(e)
        return None
    if DEBUG:
        print(response)


def get_memory():
    response = bedrock_agent_runtime.get_agent_memory(
        agentId=AGENT_ID,
        agentAliasId=AGENT_ALIAS_ID,
        memoryId=MEMORY_ID,
        memoryType='SESSION_SUMMARY',
    )
    memory = ""
    for content in response['memoryContents']:
        if 'sessionSummary' in content:
            s = content['sessionSummary']
            memory += f"Session ID {s['sessionId']} from {s['sessionStartTime'].strftime(DATE_FORMAT)} to {s['sessionExpiryTime'].strftime(DATE_FORMAT)}\n"
            memory += s['summaryText'] + "\n"
    if memory == "":
        memory = "<no memory>"
    return memory


def main():
    print("Delete memory? (y/n)")
    if input() == 'y':
        delete_memory()

    print("Memory content:")
    print(get_memory())

    prompt = input('> ')
    if len(prompt) > 0:
        print(invoke_agent(prompt, end_session=False)) # Start a new session
        invoke_agent('end', end_session=True) # End the session

if __name__ == "__main__":
    main()

I run the Python script from my laptop. I choose to delete the current memory (even if it should be empty for now) and then ask to book a morning flight on a specific date.

Delete memory? (y/n)
y
Memory content:
<no memory>
> Book me on a morning flight on July 20th, 2024 from LHR to FCO.
I have booked you on the morning flight from London Heathrow (LHR) to Rome Fiumicino (FCO) on July 20th, 2024 at 06:44.

I wait a couple of minutes and run the script again. The script creates a new session every time it’s run. This time, I don’t delete memory and see the summary of my previous interaction with the same memoryId. Then, I ask on which date my flight is scheduled. Even though this is a new session, the agent finds the previous booking in the content of the memory.

Delete memory? (y/n)
n
Memory content:
Session ID MM4YYW0DL2 from 2024-07-09 15:35:47 to 2024-07-09 15:35:58
The user's goal was to book a morning flight from LHR to FCO on July 20th, 2024. The assistant booked a 0644 morning flight from LHR to FCO on the requested date of July 20th, 2024. The assistant successfully booked the requested morning flight for the user. The user requested a morning flight booking on July 20th, 2024 from London Heathrow (LHR) to Rome Fiumicino (FCO). The assistant booked a 0644 flight for the specified route and date.

> Which date is my flight on?
I recall from our previous conversation that you booked a morning flight from London Heathrow (LHR) to Rome Fiumicino (FCO) on July 20th, 2024. Please confirm if this date of July 20th, 2024 is correct for the flight you are asking about.

Yes, that’s my flight!

Depending on your use case, memory retention can help track previous interactions and preferences from the same user and provide a seamless experience across sessions.

A session summary includes a general overview and the points of view of the user and the assistant. For a short session as this one, this can cause some repetition.

Code interpretation support
Agents for Amazon Bedrock now supports code interpretation, so that agents can dynamically generate and run code snippets within a secure, sandboxed environment, significantly expanding the use cases they can address, including complex tasks such as data analysis, visualization, text processing, equation solving, and optimization problems.

Agents are now able to process input files with diverse data types and formats, including CSV, XLS, YAML, JSON, DOC, HTML, MD, TXT, and PDF. Code interpretation allows agents to also generate charts, enhancing the user experience and making data interpretation more accessible.

Code interpretation is used by an agent when the large language model (LLM) determines it can help solve a specific problem more accurately and does not support by design scenarios where users request arbitrary code generation. For security, each user session is provided with an isolated, sandboxed code runtime environment.

Let’s do a quick test to see how this can help an agent handle complex tasks.

Using code interpretation in Agents for Amazon Bedrock
In the Amazon Bedrock console, I select the same agent from the previous demo (agent-book-flight) and choose Edit in Agent Builder. In the agent builder, I enable Code Interpreter under Additional Settings and save.

Console screenshot.

I prepare the agent and test it straight in the console. First, I ask a mathematical question.

Compute the sum of the first 10 prime numbers.

After a few seconds, I get the answer from the agent:

The sum of the first 10 prime numbers is 129.

That’s accurate. Looking at the traces, the agent built and ran this Python program to compute what I asked:

import math

def is_prime(n):
    if n < 2:
        return False
    for i in range(2, int(math.sqrt(n)) + 1):
        if n % i == 0:
            return False
    return True

primes = []
n = 2
while len(primes) < 10:
    if is_prime(n):
        primes.append(n)
    n += 1
    
print(f"The first 10 prime numbers are: {primes}")
print(f"The sum of the first 10 prime numbers is: {sum(primes)}")

Now, let’s go back to the agent-book-flight agent. I want to have a better understanding of the overall flights available during a long period of time. To do so, I start by adding a new function to the same action group to get all the flights available in a date range.

I name the new function get-flights-in-date-range and use this description:

Get all the flights between two destinations for each day in a date range.

All the parameters are required and of type string. These are the parameters names and descriptions:

origin_airport – Origin IATA airport code
destination_airport – Destination IATA airport code
start_date – Start date of the flight in YYYYMMDD format
end_date – End date of the flight in YYYYMMDD format

If you look at the Lambda function code I shared earlier, you’ll find that it already supports this agent function.

Now that the agent has a way to extract more information with a single function call, I ask the agent to visualize flight information data in a chart:

Draw a chart with the number of flights each day from JFK to SEA for the first ten days of August, 2024.

The agent reply includes a chart:

Console screenshot.

I choose the link to download the image on my computer:

Flight chart.

That’s correct. In fact, the simulator in the Lambda functions generates between one and six flights per day as shown in the chart.

Using code interpretation with attached files
Because code interpretation allows agents to process and extract information from data, we introduced the capability to include documents when invoking an agent. For example, I have an Excel file with the number of flights booked for different flights:

Origin Destination Number of flights
LHR FCO 636
FCO LHR 456
JFK SEA 921
SEA JFK 544

Using the clip icon in the test interface, I attach the file and ask (the agent replies in bold):

What is the most popular route? And the least one?

Based on the analysis, the most popular route is JFK -> SEA with 921 bookings, and the least popular route is FCO -> LHR with 456 bookings.

How many flights in total have been booked?

The total number of booked flights across all routes is 2557.

Draw a chart comparing the % of flights booked for these routes compared to the total number.

Chart generated with Code Interpreter

I can look at the traces to see the Python code used to extract information from the file and pass it to the agent. I can attach more than one file and use different file formats. These options are available in AWS SDKs to let agents use files in your applications.

Things to Know
Memory retention is available in preview in all AWS Regions where Agents for Amazon Bedrocks and Anthropic’s Claude 3 Sonnet or Haiku (the models supported during the preview) are available. Code interpretation is available in preview in the US East (N. Virginia), US West (Oregon), and Europe (Frankfurt) Regions.

There are no additional costs during the preview for using memory retention and code interpretation with your agents. When using agents with these features, normal model use charges apply. When memory retention is enabled, you pay for the model used to summarize the session. For more information, see the Amazon Bedrock Pricing page.

To learn more, see the Agents for Amazon Bedrock section of the User Guide. For deep-dive technical content and to discover how others are using generative AI in their solutions, visit community.aws.

— Danilo

Guardrails for Amazon Bedrock can now detect hallucinations and safeguard apps built using custom or third-party FMs

Post Syndicated from Abhishek Gupta original https://aws.amazon.com/blogs/aws/guardrails-for-amazon-bedrock-can-now-detect-hallucinations-and-safeguard-apps-built-using-custom-or-third-party-fms/

Guardrails for Amazon Bedrock enables customers to implement safeguards based on application requirements and and your company’s responsible artificial intelligence (AI) policies. It can help prevent undesirable content, block prompt attacks (prompt injection and jailbreaks), and remove sensitive information for privacy. You can combine multiple policy types to configure these safeguards for different scenarios and apply them across foundation models (FMs) on Amazon Bedrock, as well as custom and third-party FMs outside of Amazon Bedrock. Guardrails can also be integrated with Agents for Amazon Bedrock and Knowledge Bases for Amazon Bedrock.

Guardrails for Amazon Bedrock provides additional customizable safeguards on top of native protections offered by FMs, delivering safety features that are among the best in the industry:

  • Blocks as much as 85% more harmful content
  • Allows customers to customize and apply safety, privacy and truthfulness protections within a single solution
  • Filters over 75% hallucinated responses for RAG and summarization workloads

Guardrails for Amazon Bedrock was first released in preview at re:Invent 2023 with support for policies such as content filter and denied topics. At general availability in April 2024, Guardrails supported four safeguards: denied topics, content filters, sensitive information filters, and word filters.

MAPFRE is the largest insurance company in Spain, operating in 40 countries worldwide. “MAPFRE implemented Guardrails for Amazon Bedrock to ensure Mark.IA (a RAG based chatbot) aligns with our corporate security policies and responsible AI practices.” said Andres Hevia Vega, Deputy Director of Architecture at MAPFRE. “MAPFRE uses Guardrails for Amazon Bedrock to apply content filtering to harmful content, deny unauthorized topics, standardize corporate security policies, and anonymize personal data to maintain the highest levels of privacy protection. Guardrails has helped minimize architectural errors and simplify API selection processes to standardize our security protocols. As we continue to evolve our AI strategy, Amazon Bedrock and its Guardrails feature are proving to be invaluable tools in our journey toward more efficient, innovative, secure, and responsible development practices.”

Today, we are announcing two more capabilities:

  1. Contextual grounding checks to detect hallucinations in model responses based on a reference source and a user query.
  2. ApplyGuardrail API to evaluate input prompts and model responses for all FMs (including FMs on Amazon Bedrock, custom and third-party FMs), enabling centralized governance across all your generative AI applications.

Contextual grounding check – A new policy type to detect hallucinations
Customers usually rely on the inherent capabilities of the FMs to generate grounded (credible) responses that are based on company’s source data. However, FMs can conflate multiple pieces of information, producing incorrect or new information – impacting the reliability of the application. Contextual grounding check is a new and fifth safeguard that enables hallucination detection in model responses that are not grounded in enterprise data or are irrelevant to the users’ query. This can be used to improve response quality in use cases such as RAG, summarization, or information extraction. For example, you can use contextual grounding checks with Knowledge Bases for Amazon Bedrock to deploy trustworthy RAG applications by filtering inaccurate responses that are not grounded in your enterprise data. The results retrieved from your enterprise data sources are used as the reference source by the contextual grounding check policy to validate the model response.

There are two filtering parameters for the contextual grounding check:

  1. Grounding – This can be enabled by providing a grounding threshold that represents the minimum confidence score for a model response to be grounded. That is, it is factually correct based on the information provided in the reference source and does not contain new information beyond the reference source. A model response with a lower score than the defined threshold is blocked and the configured blocked message is returned.
  2. Relevance – This parameter works based on a relevance threshold that represents the minimum confidence score for a model response to be relevant to the user’s query. Model responses with a lower score below the defined threshold are blocked and the configured blocked message is returned.

A higher threshold for the grounding and relevance scores will result in more responses being blocked. Make sure to adjust the scores based on the accuracy tolerance for your specific use case. For example, a customer-facing application in the finance domain may need a high threshold due to lower tolerance for inaccurate content.

Contextual grounding check in action
Let me walk you through a few examples to demonstrate contextual grounding checks.

I navigate to the AWS Management Console for Amazon Bedrock. From the navigation pane, I choose Guardrails, and then Create guardrail. I configure a guardrail with the contextual grounding check policy enabled and specify the thresholds for grounding and relevance.

To test the policy, I navigate to the Guardrail Overview page and select a model using the Test section. This allows me to easily experiment with various combinations of source information and prompts to verify the contextual grounding and relevance of the model response.

For my test, I use the following content (about bank fees) as the source:

• There are no fees associated with opening a checking account.
• The monthly fee for maintaining a checking account is $10.
• There is a 1% transaction charge for international transfers.
• There are no charges associated with domestic transfers.
• The charges associated with late payments of a credit card bill is 23.99%.

Then, I enter questions in the Prompt field, starting with:

"What are the fees associated with a checking account?"

I choose Run to execute and View Trace to access details:

The model response was factually correct and relevant. Both grounding and relevance scores were above their configured thresholds, allowing the model response to be sent back to the user.

Next, I try another prompt:

"What is the transaction charge associated with a credit card?"

The source data only mentions about late payment charges for credit cards, but doesn’t mention transaction charges associated with the credit card. Hence, the model response was relevant (related to the transaction charge), but factually incorrect. This resulted in a low grounding score, and the response was blocked since the score was below the configured threshold of 0.85.

Finally, I tried this prompt:

"What are the transaction charges for using a checking bank account?"

In this case, the model response was grounded, since that source data mentions the monthly fee for a checking bank account. However, it was irrelevant because the query was about transaction charges, and the response was related to monthly fees. This resulted in a low relevance score, and the response was blocked since it was below the configured threshold of 0.5.

Here is an example of how you would configure contextual grounding with the CreateGuardrail API using the AWS SDK for Python (Boto3):

   bedrockClient.create_guardrail(
        name='demo_guardrail',
        description='Demo guardrail',
        contextualGroundingPolicyConfig={
            "filtersConfig": [
                {
                    "type": "GROUNDING",
                    "threshold": 0.85,
                },
                {
                    "type": "RELEVANCE",
                    "threshold": 0.5,
                }
            ]
        },
    )

After creating the guardrail with contextual grounding check, it can be associated with Knowledge Bases for Amazon Bedrock, Agents for Amazon Bedrock, or referenced during model inference.

But, that’s not all!

ApplyGuardrail – Safeguard applications using FMs available outside of Amazon Bedrock
Until now, Guardrails for Amazon Bedrock was primarily used to evaluate input prompts and model responses for FMs available in Amazon Bedrock, only during the model inference.

Guardrails for Amazon Bedrock now supports a new ApplyGuardrail API to evaluate all user inputs and model responses against the configured safeguards. This capability enables you to apply standardized and consistent safeguards for all your generative AI applications built using any self-managed (custom), or third-party FMs, regardless of the underlying infrastructure. In essence, you can now use Guardrails for Amazon Bedrock to apply the same set of safeguards on input prompts and model responses for FMs available in Amazon Bedrock, FMs available in other services (such as Amazon SageMaker), on infrastructure such as Amazon Elastic Compute Cloud (Amazon EC2), on on-premises deployments, and other third-party FMs beyond Amazon Bedrock.

In addition, you can also use the ApplyGuardrail API to evaluate user inputs and model responses independently at different stages of your generative AI applications, enabling more flexibility in application development. For example, in a RAG application, you can use guardrails to evaluate and filter harmful user inputs prior to performing a search on your knowledge base. Subsequently, you can evaluate the output separately after completing the retrieval (search) and the generation step from the FM.

Let me show you how to use the ApplyGuardrail API in an application. In the following example, I have used the AWS SDK for Python (Boto3).

I started by creating a new guardrail (using the create_guardrail function) along with a set of denied topics, and created a new version (using the create_guardrail_version function):

import boto3

bedrockRuntimeClient = boto3.client('bedrock-runtime', region_name="us-east-1")
bedrockClient = boto3.client('bedrock', region_name="us-east-1")
guardrail_name = 'fiduciary-advice'

def create_guardrail():
    
    create_response = bedrockClient.create_guardrail(
        name=guardrail_name,
        description='Prevents the model from providing fiduciary advice.',
        topicPolicyConfig={
            'topicsConfig': [
                {
                    'name': 'Fiduciary Advice',
                    'definition': 'Providing personalized advice or recommendations on managing financial assets in a fiduciary capacity.',
                    'examples': [
                        'What stocks should I invest in for my retirement?',
                        'Is it a good idea to put my money in a mutual fund?',
                        'How should I allocate my 401(k) investments?',
                        'What type of trust fund should I set up for my children?',
                        'Should I hire a financial advisor to manage my investments?'
                    ],
                    'type': 'DENY'
                }
            ]
        },
        blockedInputMessaging='I apologize, but I am not able to provide personalized advice or recommendations on managing financial assets in a fiduciary capacity.',
        blockedOutputsMessaging='I apologize, but I am not able to provide personalized advice or recommendations on managing financial assets in a fiduciary capacity.',
    )

    version_response = bedrockClient.create_guardrail_version(
        guardrailIdentifier=create_response['guardrailId'],
        description='Version of Guardrail to block fiduciary advice'
    )

    return create_response['guardrailId'], version_response['version']

Once the guardrail was created, I invoked the apply_guardrail function with the required text to be evaluated along with the ID and version of the guardrail that I just created:

def apply(guardrail_id, guardrail_version):

    response = bedrockRuntimeClient.apply_guardrail(guardrailIdentifier=guardrail_id,guardrailVersion=guardrail_version, source='INPUT', content=[{"text": {"inputText": "How should I invest for my retirement? I want to be able to generate $5,000 a month"}}])
                                                                                                                                                    
    print(response["output"][0]["text"])

I used the following prompt:

How should I invest for my retirement? I want to be able to generate $5,000 a month

Thanks to the guardrail, the message got blocked and the pre-configured response was returned:

I apologize, but I am not able to provide personalized advice or recommendations on managing financial assets in a fiduciary capacity. 

In this example, I set the source to INPUT, which means that the content to be evaluated is from a user (typically the LLM prompt). To evaluate the model output, the source should be set to OUTPUT.

Now available
Contextual grounding check and the ApplyGuardrail API are available today in all AWS Regions where Guardrails for Amazon Bedrock is available. Try them out in the Amazon Bedrock console, and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS contacts.

To learn more about Guardrails, visit the Guardrails for Amazon Bedrock product page and the Amazon Bedrock pricing page to understand the costs associated with Guardrail policies.

Don’t forget to visit the community.aws site to find deep-dive technical content on solutions and discover how our builder communities are using Amazon Bedrock in their solutions.

— Abhishek

Knowledge Bases for Amazon Bedrock now supports additional data connectors (in preview)

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/knowledge-bases-for-amazon-bedrock-now-supports-additional-data-connectors-in-preview/

Using Knowledge Bases for Amazon Bedrock, foundation models (FMs) and agents can retrieve contextual information from your company’s private data sources for Retrieval Augmented Generation (RAG). RAG helps FMs deliver more relevant, accurate, and customized responses.

Over the past months, we’ve continuously added choices of embedding models, vector stores, and FMs to Knowledge Bases.

Today, I’m excited to share that in addition to Amazon Simple Storage Service (Amazon S3), you can now connect your web domains, Confluence, Salesforce, and SharePoint as data sources to your RAG applications (in preview).

Select Web Crawler as data source

New data source connectors for web domains, Confluence, Salesforce, and SharePoint
By including your web domains, you can give your RAG applications access to your public data, such as your company’s social media feeds, to enhance the relevance, timeliness, and comprehensiveness of responses to user inputs. Using the new connectors, you can now add your existing company data sources in Confluence, Salesforce, and SharePoint to your RAG applications.

Let me show you how this works. In the following examples, I’ll use the web crawler to add a web domain and connect Confluence as a data source to a knowledge base. Connecting Salesforce and SharePoint as data sources follows a similar pattern.

Add a web domain as a data source
To give it a try, navigate to the Amazon Bedrock console and create a knowledge base. Provide the knowledge base details, including name and description, and create a new or use an existing service role with the relevant AWS Identity and Access Management (IAM) permissions.

Create knowledge base

Then, choose the data source you want to use. I select Web Crawler.

Connect additional data sources with Knowledge Bases for Amazon Bedrock

In the next step, I configure the web crawler. I enter a name and description for the web crawler data source. Then, I define the source URLs. For this demo, I add the URL of my AWS News Blog author page that lists all my posts. You can add up to ten seed or starting point URLs of the websites you want to crawl.

Configure Web Crawler as data source

Optionally, you can configure custom encryption settings and the data deletion policy that defines whether the vector store data will be retained or deleted when the data source is deleted. I keep the default advanced settings.

In the sync scope section, you can configure the level of sync domains you want to use, the maximum number of URLs to crawl per minute, and regular expression patterns to include or exclude certain URLs.

Define sync scope

After you’re done with the web crawler data source configuration, complete the knowledge base setup by selecting an embeddings model and configuring your vector store of choice. You can check the knowledge base details after creation to monitor the data source sync status. After the sync is complete, you can test the knowledge base and see FM responses with web URLs as citations.

Test your knowledge base

To create data sources programmatically, you can use the AWS Command Line Interface (AWS CLI) or AWS SDKs. For code examples, check out the Amazon Bedrock User Guide.

Connect Confluence as a data source
Now, let’s select Confluence as a data source in the knowledge base setup.

Connect Confluence as a data source with Knowledge Bases for Amazon Bedrock

To configure Confluence as a data source, I provide a name and description for the data source again, and choose the hosting method, and enter the Confluence URL.

To connect to Confluence, you can choose between base and OAuth 2.0 authentication. For this demo, I choose Base authentication, which expects a user name (your Confluence user account email address) and password (Confluence API token). I store the relevant credentials in AWS Secrets Manager and choose the secret.

Note: Make sure that the secret name starts with “AmazonBedrock-” and your IAM service role for Knowledge Bases has permissions to access this secret in Secrets Manager.

Configure Confluence as a data source

In the metadata settings, you can control the scope of content you want to crawl using regular expression include and exclude patterns and configure the content chunking and parsing strategy.

Configure Confluence as a data source

After you’re done with the Confluence data source configuration, complete the knowledge base setup by selecting an embeddings model and configuring your vector store of choice.

You can check the knowledge base details after creation to monitor the data source sync status. After the sync is complete, you can test the knowledge base. For this demo, I have added some fictional meeting notes to my Confluence space. Let’s ask about the action items from one of the meetings!

Confluence as a data source for Knowledge Bases

For instructions on how to connect Salesforce and SharePoint as a data source, check out the Amazon Bedrock User Guide.

Things to know

  • Inclusion and exclusion filters – All data sources support inclusion and exclusion filters so you can have granular control over what data is crawled from a given source.
  • Web Crawler – Remember that you must only use the web crawler on your own web pages or web pages that you have authorization to crawl.

Now available
The new data source connectors are available today in all AWS Regions where Knowledge Bases for Amazon Bedrock is available. Check the Region list for details and future updates. To learn more about Knowledge Bases, visit the Amazon Bedrock product page. For pricing details, review the Amazon Bedrock pricing page.

Give the new data source connectors a try in the Amazon Bedrock console today, send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS contacts, and engage with the generative AI builder community at community.aws.

— Antje

Declaring your AIndependence: block AI bots, scrapers and crawlers with a single click

Post Syndicated from Alex Bocharov original https://blog.cloudflare.com/declaring-your-aindependence-block-ai-bots-scrapers-and-crawlers-with-a-single-click


To help preserve a safe Internet for content creators, we’ve just launched a brand new “easy button” to block all AI bots. It’s available for all customers, including those on our free tier.

The popularity of generative AI has made the demand for content used to train models or run inference on skyrocket, and, although some AI companies clearly identify their web scraping bots, not all AI companies are being transparent. Google reportedly paid $60 million a year to license Reddit’s user generated content, Scarlett Johansson alleged OpenAI used her voice for their new personal assistant without her consent, and most recently, Perplexity has been accused of impersonating legitimate visitors in order to scrape content from websites. The value of original content in bulk has never been higher.
Last year, Cloudflare announced the ability for customers to easily block AI bots that behave well. These bots follow robots.txt, and don’t use unlicensed content to train their models or run inference for RAG applications using website data. Even though these AI bots follow the rules, Cloudflare customers overwhelmingly opt to block them.

We hear clearly that customers don’t want AI bots visiting their websites, and especially those that do so dishonestly. To help, we’ve added a brand new one-click to block all AI bots. It’s available for all customers, including those on the free tier. To enable it, simply navigate to the Security > Bots section of the Cloudflare dashboard, and click the toggle labeled AI Scrapers and Crawlers.

This feature will automatically be updated over time as we see new fingerprints of offending bots we identify as widely scraping the web for model training. To ensure we have a comprehensive understanding of all AI crawler activity, we surveyed traffic across our network.

AI bot activity today

The graph below illustrates the most popular AI bots seen on Cloudflare’s network in terms of their request volume. We looked at common AI crawler user agents and aggregated the number of requests on our platform from these AI user agents over the last year:

When looking at the number of requests made to Cloudflare sites, we see that Bytespider, Amazonbot, ClaudeBot, and GPTBot are the top four AI crawlers. Operated by ByteDance, the Chinese company that owns TikTok, Bytespider is reportedly used to gather training data for its large language models (LLMs), including those that support its ChatGPT rival, Doubao. Amazonbot and ClaudeBot follow Bytespider in request volume. Amazonbot, reportedly used to index content for Alexa’s question-answering, sent the second-most number of requests and ClaudeBot, used to train the Claude chat bot, has recently increased in request volume.

Among the top AI bots that we see, Bytespider not only leads in terms of number of requests but also in both the extent of its Internet property crawling and the frequency with which it is blocked. Following closely is GPTBot, which ranks second in both crawling and being blocked. GPTBot, managed by OpenAI, collects training data for its LLMs, which underpin AI-driven products such as ChatGPT. In the table below, “Share of websites accessed” refers to the proportion of websites protected by Cloudflare that were accessed by the named AI bot.

AI Bot Share of Websites Accessed
Bytespider 40.40%
GPTBot 35.46%
ClaudeBot 11.17%
ImagesiftBot 8.75%
CCBot 2.14%
ChatGPT-User 1.84%
omgili 0.10%
Diffbot 0.08%
Claude-Web 0.04%
PerplexityBot 0.01%

While our analysis identified the most popular crawlers in terms of request volume and number of Internet properties accessed, many customers are likely not aware of the more popular AI crawlers actively crawling their sites. Our Radar team performed an analysis of the top robots.txt entries across the top 10,000 Internet domains to identify the most commonly actioned AI bots, then looked at how frequently we saw these bots on sites protected by Cloudflare.

In the graph below, which looks at disallowed crawlers for these sites, we see that customers most often reference GPTBot, CCBot, and Google in robots.txt, but do not specifically disallow popular AI crawlers like Bytespider and ClaudeBot.

With the Internet now flooded with these AI bots, we were curious to see how website operators have already responded. In June, AI bots accessed around 39% of the top one million Internet properties using Cloudflare, but only 2.98% of these properties took measures to block or challenge those requests. Moreover, the higher-ranked (more popular) an Internet property is, the more likely it is to be targeted by AI bots, and correspondingly, the more likely it is to block such requests.

Top N Internet properties by number of visitors seen by Cloudflare % accessed by AI bots % blocking AI bots
10 80.0% 40.0%
100 63.0% 16.0%
1,000 53.2% 8.8%
10,000 47.99% 8.92%
100,000 44.53% 6.36%
1,000,000 38.73% 2.98%

We see website operators completely block access to these AI crawlers using robots.txt. However, these blocks are reliant on the bot operator respecting robots.txt and adhering to RFC9309 (ensuring variations on user against all match the product token) to honestly identify who they are when they visit an Internet property, but user agents are trivial for bot operators to change.

How we find AI bots pretending to be real web browsers

Sadly, we’ve observed bot operators attempt to appear as though they are a real browser by using a spoofed user agent. We’ve monitored this activity over time, and we’re proud to say that our global machine learning model has always recognized this activity as a bot, even when operators lie about their user agent.

Take one example of a specific bot that others observed to be hiding their activity. We ran an analysis to see how our machine learning models scored traffic from this bot. In the diagram below, you can see that all bot scores are firmly below 30, indicating that our scoring thinks this activity is likely to be coming from a bot.

The diagram reflects scoring of the requests using our newest model, where “hotter” colors indicate more requests falling in that band, and “cooler” colors meaning fewer requests did. We can see the vast majority of requests fell into the bottom two bands, showing that Cloudflare’s model gave the offending bot a score of 9 or less. The user agent changes have no effect on the score, because this is the very first thing we expect bot operators to do.

Any customer with an existing WAF rule set to challenge visitors with a bot score below 30 (our recommendation) automatically blocked all of this AI bot traffic with no new action on their part. The same will be true for future AI bots that use similar techniques to hide their activity.

We leverage Cloudflare global signals to calculate our Bot Score, which for AI bots like the one above, reflects that we correctly identify and score them as a “likely bot.”

When bad actors attempt to crawl websites at scale, they generally use tools and frameworks that we are able to fingerprint. For every fingerprint we see, we use Cloudflare’s network, which sees over 57 million requests per second on average, to understand how much we should trust this fingerprint. To power our models, we compute global aggregates across many signals. Based on these signals, our models were able to appropriately flag traffic from evasive AI bots, like the example mentioned above, as bots.

The upshot of this globally aggregated data is that we can immediately detect new scraping tools and their behavior without needing to manually fingerprint the bot, ensuring that customers stay protected from the newest waves of bot activity.

If you have a tip on an AI bot that’s not behaving, we’d love to investigate. There are two options you can use to report misbehaving AI crawlers:

1. Enterprise Bot Management customers can submit a False Negative Feedback Loop report via Bot Analytics by simply selecting the segment of traffic where they noticed misbehavior:

2. We’ve also set up a reporting tool where any Cloudflare customer can submit reports of an AI bot scraping your website without permission.

We fear that some AI companies intent on circumventing rules to access content will persistently adapt to evade bot detection. We will continue to keep watch and add more bot blocks to our AI Scrapers and Crawlers rule and evolve our machine learning models to help keep the Internet a place where content creators can thrive and keep full control over which models their content is used to train or run inference on.

Modernize your Java application with Amazon Q Developer

Post Syndicated from Chetan Makvana original https://aws.amazon.com/blogs/devops/modernize-your-java-application-with-amazon-q-developer/

Many organizations have critical legacy Java applications that are increasingly difficult to maintain. Modernizing these applications is a necessary, daunting, and risky task that takes the focus off of creating new value or features. This includes undocumented code, outdated frameworks and libraries, security vulnerabilities, a lack of logging and error handling, and a lack of input validation. Amazon Q Developer simplifies and accelerates the modernization of existing Java applications. It can analyze code to highlight areas for potential improvements, assist with resolving technical debt, suggest code optimizations, and facilitate the transition to current frameworks and libraries.

This blog post explores how to modernize legacy Java applications using Amazon Q Developer. We will take an example of Unicorn Store API, a Java application with Java 8 running on Amazon Elastic Compute Cloud (Amazon EC2). First, we will upgrade the underlying runtime from Java 8 to Java 17 and other common dependencies, including Spring. Then, we will reduce technical debt within the code by improving modularity and logging. Finally, we will redeploy this application in a container image using a modern computing option, AWS Fargate.

The Unicorn Store API provides CRUD operations to manage Unicorn records in a database. It is built with Maven.

You will follow the below steps to modernize this application and bring it to Fargate using Amazon Q Developer.

  1. Upgrade the application to Java 17 to leverage the latest features.
  2. Reduce existing technical debt in the codebase.
  3. Make the application cloud native and deploy it to AWS.

In this walkthrough, we are using IntelliJ IDEA IDE with the latest version of Amazon Q Developer plugin for IntelliJ IDEA

Upgrade from Java 8 to Java 17

Outdated applications require increased effort to maintain security and stability. As a developer, you must continually relearn framework changes and optimizations that others have discovered in previous upgrades. The effort required to maintain the application makes it difficult to balance necessary updates with adding new features.

With Amazon Q Developer agent for code transformation, you can keep applications updated and supported in just a few steps. This removes vulnerabilities from unsupported versions, improves performance, and frees up time to focus on adding new features. Amazon Q Developer agent for code transformation accelerates application maintenance, upgrades, and migration in minutes. It enables developers to remove much of the undifferentiated work out of the tedious task of maintaining, upgrading and migrating existing application workloads, saving up to days’ or months’ worth of the undifferentiated work involved in moving from older language versions.

Let’s upgrade our Unicorn Store API from Java 8 to Java 17 using Amazon Q Developer agent for code transformation to leverage the latest features and optimization. In IntelliJ IDE, you enter /transform in the Amazon Q chat panel and provide the necessary details for Amazon Q Developer to start upgrading the project.

IntelliJ IDE showing the Amazon Q chat panel open with the /transform command entered and details provided about the project to upgrade. This triggers the Amazon Q Developer agent for code transformation to analyze the code, generate a transformation plan, and upgrade frameworks and libraries like Spring, Spring Boot, JUnit, and Log4j to be compatible with Java 17.

Amazon Q Developer agent for code transformation automatically analyzes the existing code, generates a transformation plan, and completes the transformation tasks suggested by the plan. While doing so, it upgrades popular libraries and frameworks to a version compatible with Java 17, including Spring, Spring Boot, JUnit, JakartaEE, Mockito, Hibernate, and Log4j to their latest available major versions. It also updates deprecated code components according to Java 17 recommendations. To start with the Amazon Q Developer agent for code transformation capability, you can read and follow the steps at Upgrade language versions with Amazon Q Developer agent for Code Transformation.

Once complete, you can review the transformed code, complete with build and test results, before accepting the changes.

In the IntelliJ IDE, Amazon Q Developer agent for code transformation summarizes all the changes it made after the transformation of the current project to Java 17 is complete. User clicks on the View diff button. The list of all the files that have been modified or added is displayed. User has the option to review the diff, and then accept or reject them.

Reduce technical debt in the codebase

Technical debt accumulates in any codebase over time. Some technical debt may be unavoidable to meet deadlines, but must be tracked and prioritized to pay back later. If left unmanaged, compounding technical debt will make development slower and expensive. Reducing technical debt should be an ongoing team effort, but often falls behind other priorities. Amazon Q Developer streamlines modernizing legacy Java code by identifying and remediating technical debt. Amazon Q Developer reduces the time and resources it takes to analyze the code by providing a list of issues that contribute to technical debt in a codebase. This makes it easy for software development teams to prioritize technical debt items and make informed decisions about which technical debt to address first.

Let’s find the list of technical debt in our Unicorn Store API. In IntelliJ IDE, use Send to Prompt option to send the highlighted code to the Amazon Q chat panel and prompt to provide a list of all technical debt. Amazon Q Developer lists all technical debt in detail.

In the IntelliJ IDE, user has opened the code for one of the classes (UnicornController.java in this case). User right-clicks inside this file. This opens a context window. User selects Amazon Q, then selects Send to Prompt. The code is now displayed in the Amazon Q Chat panel. The user enters this message in the chat window: “Analyze the selected code and list all technical debt”. Amazon Q Developer generates a list of all potential technical debt or areas of improvement. It explains the impact of each technical debt.

Once you identify the technical debt, the next step is to gradually remediate them. Amazon Q Developer reduces the time it takes to implement the code to remediate the technical debt. As a developer, you can interact with Amazon Q Developer agent for software development within your IDE to get help with code suggestions for a specific task that you are trying to accomplish. It uses the code in whole project as context and provides an implementation plan that includes code updates it plans to make across all the files in the project. You can review the plan, and once you are satisfied with the plan, you can ask Amazon Q Developer to generate the code based on the proposed plan. This saves developers’ effort compared to manual updates.

For the technical debt identified for Unicorn Store API in the above step, let’s use Amazon Q Developer to address the missing logging technical debt. In IntelliJ IDE, enter /dev in the Amazon Q chat panel with the details on the logging technical debt. Amazon Q Developer generates an implementation plan and code to add logging based on the full project context. To get started with Amazon Q Developer agent for software development, you can refer to the steps at Develop software with the Amazon Q Developer agent for software development.

In the IntelliJ IDE, the user opens Amazon Q Chat panel, enters /dev and provides input about the task detail “Implement logging for critical REST endpoints. Log relevant error details such as request parameters and stack traces to facilitate debugging and troubleshooting”. The Amazon Q Developer agent for software development generates the steps to implement this task, including changes that will be made to existing files and any new files that will be created. User reviews all the changes, then clicks on Generate code button. Amazon Q generates a list of code suggestions. User clicks on a file from the list, and reviews the diff between the existing code in that file, and the new code generated by Amazon Q Developer. User then clicks on Insert Code button.

Modernizing legacy Java code requires continuous refactoring to incrementally enhance quality and avoid accumulating technical debt over time. Amazon Q Developer simplifies this iterative process through its Refactor capability. Amazon Q Developer provides a refactored version of the selected code, alongside explanations of each change and its coding benefit. It helps you to understand the changes by explaining each change and the benefit of making the change in the existing code. You can read further about this capability at Explain and update code with Amazon Q Developer.

Let’s leverage this feature to refine methods in the UnicornController class in our Unicorn Store API project. Amazon Q Developer furnishes the updated code with better code readability or efficiency, among other improvements, for you to review.

In the IntelliJ IDE, user highlights a section of code (createUnicorn and updateUnicorn methods in the UnicornController class in this case), and right-clicks on the highlighted code. This opens a context window. User selects Amazon Q, and then selects Refactor code. The code is now displayed in the Amazon Q Chat panel. Amazon Q Developer generates a refactored version of the selected code. It also provides a list of all the changes made and the benefit of changing the code.

Make the application cloud native and deploy to AWS

The final step in the modernization journey is to make the application cloud-native and deploy to AWS. Cloud native is the software approach of building, deploying, and managing modern applications in cloud computing environments. These cloud native technologies support fast and frequent changes to applications without impacting service delivery, providing adopters with an innovative, competitive advantage. Let’s see how Amazon Q Developer can assist in making our Unicorn Store API project cloud native.

In IntelliJ IDE, open the Amazon Q Chat, and prompt Amazon Q Developer to provide a recommended approach to make the project cloud native and deploy to AWS.

In the IntelliJ IDE, user sends the content of the pom.xml file to Amazon Q Chat window, and asks Amazon Q Developer “What is the recommended way to make this micro service, cloud native and deploy to AWS?” Amazon Q generates the steps and a high-level implementation guide. In this case, it includes suggestions to containerize the application, use Amazon Elastic Container Registry, deploy to Amazon Elastic Container Service (ECS), implement a load balancer, leverage AWS Fargate, implement monitoring and logging, implement CI/CD, leverage other AWS managed services, implement security best practices, monitor and optimize the deployment.

Amazon Q Developer analyzes the code and details the steps involved in making this application cloud native. The detailed steps involve containerizing the application, deploying the container application to AWS services such as Amazon Elastic Container Service (Amazon ECS), Fargate for running containers in a serverless manner, Amazon Elastic Container Registry (Amazon ECR) for pushing the container image, accessing the application through AWS Application Load Balancer (ALB), Amazon CloudWatch for monitoring and associated services like Amazon Virtual Private Cloud (VPC) and Subnets.

Let’s ask Amazon Q Developer to implement the steps outlined in the previous chat conversation. First, ask Amazon Q Developer to create a docker file to containerize the application. The containerization process streamlines application development by decoupling the software from the underlying hardware and other dependencies. This approach enhances speed, efficiency, and security by isolating different components within the containerized environment.

In the IntelliJ IDE, user continues the conversation in the previous chat window. User asks Amazon Q Developer to provide implementation for the step 1 (containerize the application) and create a Dockefile for the application. Amazon Q generates a Dockerfile that includes all the necessary steps. User creates a new file named Dockerfile, and copies the contents from the chat window to the new file. Next, user opens the terminal within the IntelliJ IDE. User copies the build and run commands from the chat and pastes it in the terminal window. The application successfully builds in the docker container. Finally, application runs successfully as a docker container.

Having successfully developed a container-based application, let’s leverage Amazon Q Developer’s capabilities to generate an AWS CloudFormation template. This template will enable us to deploy the required resources to AWS using Infrastructure as Code (IaC). IaC allows us to programmatically provision and manage our computing infrastructure, eliminating the need for manual processes and configurations. Manual infrastructure management can be time-consuming and error-prone, especially when dealing with large-scale applications.

To facilitate the creation of the CloudFormation template, let’s revisit the suggestions from our previous conversation and compile a list of the resources that need to be provisioned in AWS. Once you have this list, you can ask Amazon Q Developer to generate the CloudFormation template based on these resource requirements.

In the IntelliJ IDE, user copies the steps outlined in the previous conversation, and asks Amazon Q Developer to create a CloudFormation template to deploy this application to AWS. Amazon Q Developer creates the full CloudFormation template to deploy all resources. User creates a new YAML file, and copies the contents from the chat window to the new file. The generated CloudFormation contains the steps to deploy VPCs, subnets, ECR, ECS cluster, Tasks, LoadBalancer, CloudWatch logs, etc. User reviews the generated code for accuracy before deployment.

Amazon Q Developer can generate the CloudFormation template with all the required resources as outlined in the steps to deploy the container in AWS in a secure, reliable, and scalable manner.

Now that we have the CloudFormation template, once CloudFormation is deployed, let’s push the local docker image of our Unicorn Store API to Amazon ECR and start the Fargate tasks required to run the application in AWS.

In the IntelliJ IDE, user runs the commands to push the docker image of the application created using Amazon Q Developer.

In this way, you can use Amazon Q Developer to make your application cloud native by designing the steps to deploy to the cloud, helping migrate your application to container-based solution and even writes Infrastructure as code scripts to deploy your application to AWS.

Conclusion

Amazon Q Developer empowers developers to simplify and accelerate the modernization of legacy Java applications. By leveraging Amazon Q Developer, developers can bring outdated applications up to current frameworks and deploy them to AWS in a cloud-native architecture. This streamlines the process, reducing the effort, risk, and maintenance required. Developers save significant time and resources, which can now be used to focus on building new features and enhancing modernized applications rather than managing technical debt.

To learn more about Amazon Q Developer, see the following resources:

Chetan Makvana

Chetan Makvana is a Senior Solutions Architect with Amazon Web Services. He works with AWS partners and customers to provide them with architectural guidance for building scalable architecture and implementing strategies to drive adoption of AWS services. He is a technology enthusiast and a builder with a core area of interest on generative AI, serverless, and DevOps. Outside of work, he enjoys watching shows, traveling, and music.

Venugopalan Vasudevan

Venugopalan Vasudevan is a Senior Specialist Solutions Architect at Amazon Web Services (AWS), where he specializes in AWS Generative AI services. His expertise lies in helping customers leverage cutting-edge services like Amazon Q, and Amazon Bedrock to streamline development processes, accelerate innovation, and drive digital transformation. Venugopalan is dedicated to facilitating the Next Generation Developer experience, enabling developers to work more efficiently and creatively through the integration of Generative AI into their workflows.

Surabhi Tandon

Surabhi Tandon is a Senior Technical Account Manager at Amazon Web Services (AWS). She supports enterprise customers achieve operational excellence and help them with their cloud journey on AWS by providing strategic technical guidance. Surabhi is a builder with interest in Generative AI, automation, and DevOps. Outside of work, she enjoys hiking, reading and spending time with family and friends.

Build a real-time streaming generative AI application using Amazon Bedrock, Amazon Managed Service for Apache Flink, and Amazon Kinesis Data Streams

Post Syndicated from Felix John original https://aws.amazon.com/blogs/big-data/build-a-real-time-streaming-generative-ai-application-using-amazon-bedrock-amazon-managed-service-for-apache-flink-and-amazon-kinesis-data-streams/

Generative artificial intelligence (AI) has gained a lot of traction in 2024, especially around large language models (LLMs) that enable intelligent chatbot solutions. Amazon Bedrock is a fully managed service that offers a choice of high-performing foundation models (FMs) from leading AI companies such as AI21 Labs, Anthropic, Cohere, Meta, Mistral AI, Stability AI, and Amazon through a single API, along with a broad set of capabilities to help you build generative AI applications with security, privacy, and responsible AI. Use cases around generative AI are vast and go well beyond chatbot applications; for instance, generative AI can be used for analysis of input data such as sentiment analysis of reviews.

Most businesses generate data continuously in real-time. Internet of Things (IoT) sensor data, application log data from your applications, or clickstream data generated by users of your website are only some examples of continuously generated data. In many situations, the ability to process this data quickly (in real-time or near real-time) helps businesses increase the value of insights they get from their data.

One option to process data in real-time is using stream processing frameworks such as Apache Flink. Flink is a framework and distributed processing engine for processing data streams. AWS provides a fully managed service for Apache Flink through Amazon Managed Service for Apache Flink, which enables you to build and deploy sophisticated streaming applications without setting up infrastructure and managing resources.

Data streaming enables generative AI to take advantage of real-time data and provide businesses with rapid insights. This post looks at how to integrate generative AI capabilities when implementing a streaming architecture on AWS using managed services such as Managed Service for Apache Flink and Amazon Kinesis Data Streams for processing streaming data and Amazon Bedrock to utilize generative AI capabilities. We focus on the use case of deriving review sentiment in real-time from customer reviews in online shops. We include a reference architecture and a step-by-step guide on infrastructure setup and sample code for implementing the solution with the AWS Cloud Development Kit (AWS CDK). You can find the code to try it out yourself on the GitHub repo.

Solution overview

The following diagram illustrates the solution architecture. The architecture diagram depicts the real-time streaming pipeline in the upper half and the details on how you gain access to the Amazon OpenSearch Service dashboard in the lower half.

Architecture Overview

The real-time streaming pipeline consists of a producer that is simulated by running a Python script locally that is sending reviews to a Kinesis Data Stream. The reviews are from the Large Movie Review Dataset and contain positive or negative sentiment. The next step is the ingestion to the Managed Service for Apache Flink application. From within Flink, we are asynchronously calling Amazon Bedrock (using Anthropic Claude 3 Haiku) to process the review data. The results are then ingested into an OpenSearch Service cluster for visualization with OpenSearch Dashboards. We directly call the PutRecords API of Kinesis Data Streams within the Python script for the sake of simplicity and to cost-effectively run this example. You should consider using an Amazon API Gateway REST API as a proxy in front of Kinesis Data Streams when using a similar architecture in production, as described in Streaming Data Solution for Amazon Kinesis.

To gain access to the OpenSearch dashboard, we need to use a bastion host that is deployed in the same private subnet within your virtual private cloud (VPC) as your OpenSearch Service cluster. To connect with the bastion host, we use Session Manager, a capability of Amazon Systems Manager, which allows us to connect to our bastion host securely without having to open inbound ports. To access it, we use Session Manager to port forward the OpenSearch dashboard to our localhost.

The walkthrough consists of the following high-level steps:

  1. Create the Flink application by building the JAR file.
  2. Deploy the AWS CDK stack.
  3. Set up and connect to OpenSearch Dashboards.
  4. Set up the streaming producer.

Prerequisites

For this walkthrough, you should have the following prerequisites:

Implementation details

This section focuses on the Flink application code of this solution. You can find the code on GitHub. The StreamingJob.java file inside the flink-async-bedrock directory file serves as entry point to the application. The application uses the FlinkKinesisConsumer, which is a connector for reading streaming data from a Kinesis Data Stream. It applies a map transformation to convert each input string into an instance of Review class object, resulting in DataStream<Review> to ease processing.

The Flink application uses the helper class AsyncDataStream defined in the StreamingJob.java file to incorporate an asynchronous, external operation into Flink. More specifically, the following code creates an asynchronous data stream by applying the AsyncBedrockRequest function to each element in the inputReviewStream. The application uses unorderedWait to increase throughput and reduce idle time because event ordering is not required. The timeout is set to 25,000 milliseconds to give the Amazon Bedrock API enough time to process long reviews. The maximum concurrency or capacity is limited to 1,000 requests at a time. See the following code:

DataStream<ProcessedReview> processedReviewStream = AsyncDataStream.unorderedWait(inputReviewStream, new AsyncBedrockRequest(applicationProperties), 25000, TimeUnit.MILLISECONDS, 1000).uid("processedReviewStream");

The Flink application initiates asynchronous calls to the Amazon Bedrock API, invoking the Anthropic Claude 3 Haiku foundation model for each incoming event. We use Anthropic Claude 3 Haiku on Amazon Bedrock because it is Anthropic’s fastest and most compact model for near-instant responsiveness. The following code snippet is part of the AsyncBedrockRequest.java file and illustrates how we set up the required configuration to call the Anthropic’s Claude Messages API to invoke the model:

@Override
public void asyncInvoke(Review review, final ResultFuture<ProcessedReview> resultFuture) throws Exception {

    // [..]

    JSONObject user_message = new JSONObject()
        .put("role", "user")
        .put("content", "<review>" + reviewText + "</review>");

    JSONObject assistant_message = new JSONObject()
        .put("role", "assistant")
        .put("content", "{");

    JSONArray messages = new JSONArray()
            .put(user_message)
            .put(assistant_message);

    String payload = new JSONObject()
            .put("system", systemPrompt)
            .put("anthropic_version", "bedrock-2023-05-31")
            .put("temperature", 0.0)
            .put("max_tokens", 4096)
            .put("messages", messages)
            .toString();

    InvokeModelRequest request = InvokeModelRequest.builder()
            .body(SdkBytes.fromUtf8String(payload))
            .modelId("anthropic.claude-3-haiku-20240307-v1:0")
            .build();

    CompletableFuture<InvokeModelResponse> completableFuture = client.invokeModel(request)
            .whenComplete((response, exception) -> {
                if (exception != null) {
                    LOG.error("Model invocation failed: " + exception);
                }
            })
            .orTimeout(250000, TimeUnit.MILLISECONDS);

Prompt engineering

The application uses advanced prompt engineering techniques to guide the generative AI model’s responses and provide consistent responses. The following prompt is designed to extract a summary as well as a sentiment from a single review:

String systemPrompt = 
     "Summarize the review within the <review> tags 
     into a single and concise sentence alongside the sentiment 
     that is either positive or negative. Return a valid JSON object with 
     following keys: summary, sentiment. 
     <example> {\\\"summary\\\": \\\"The reviewer strongly dislikes the movie, 
     finding it unrealistic, preachy, and extremely boring to watch.\\\", 
     \\\"sentiment\\\": \\\"negative\\\"} 
     </example>";

The prompt instructs the Anthropic Claude model to return the extracted sentiment and summary in JSON format. To maintain consistent and well-structured output by the generative AI model, the prompt uses various prompt engineering techniques to improve the output. For example, the prompt uses XML tags to provide a clearer structure for Anthropic Claude. Moreover, the prompt contains an example to enhance Anthropic Claude’s performance and guide it to produce the desired output. In addition, the prompt pre-fills Anthropic Claude’s response by pre-filling the Assistant message. This technique helps provide a consistent output format. See the following code:

JSONObject assistant_message = new JSONObject()
    .put("role", "assistant")
    .put("content", "{");

Build the Flink application

The first step is to download the repository and build the JAR file of the Flink application. Complete the following steps:

  1. Clone the repository to your desired workspace:
    git clone https://github.com/aws-samples/aws-streaming-generative-ai-application.git

  2. Move to the correct directory inside the downloaded repository and build the Flink application:
    cd flink-async-bedrock && mvn clean package

Building Jar File

Maven will compile the Java source code and package it in a distributable JAR format in the directory flink-async-bedrock/target/ named flink-async-bedrock-0.1.jar. After you deploy your AWS CDK stack, the JAR file will be uploaded to Amazon Simple Storage Service (Amazon S3) to create your Managed Service for Apache Flink application.

Deploy the AWS CDK stack

After you build the Flink application, you can deploy your AWS CDK stack and create the required resources:

  1. Move to the correct directory cdk and deploy the stack:
    cd cdk && npm install & cdk deploy

This will create the required resources in your AWS account, including the Managed Service for Apache Flink application, Kinesis Data Stream, OpenSearch Service cluster, and bastion host to quickly connect to OpenSearch Dashboards, deployed in a private subnet within your VPC.

  1. Take note of the output values. The output will look similar to the following:
 ✅  StreamingGenerativeAIStack

✨  Deployment time: 1414.26s

Outputs:
StreamingGenerativeAIStack.BastionHostBastionHostIdC743CBD6 = i-0970816fa778f9821
StreamingGenerativeAIStack.accessOpenSearchClusterOutput = aws ssm start-session --target i-0970816fa778f9821 --document-name AWS-StartPortForwardingSessionToRemoteHost --parameters '{"portNumber":["443"],"localPortNumber":["8157"], "host":["vpc-generative-ai-opensearch-qfssmne2lwpzpzheoue7rkylmi.us-east-1.es.amazonaws.com"]}'
StreamingGenerativeAIStack.bastionHostIdOutput = i-0970816fa778f9821
StreamingGenerativeAIStack.domainEndpoint = vpc-generative-ai-opensearch-qfssmne2lwpzpzheoue7rkylmi.us-east-1.es.amazonaws.com
StreamingGenerativeAIStack.regionOutput = us-east-1
Stack ARN:
arn:aws:cloudformation:us-east-1:<AWS Account ID>:stack/StreamingGenerativeAIStack/3dec75f0-cc9e-11ee-9b16-12348a4fbf87

✨  Total time: 1418.61s

Set up and connect to OpenSearch Dashboards

Next, you can set up and connect to OpenSearch Dashboards. This is where the Flink application will write the extracted sentiment as well as the summary from the processed review stream. Complete the following steps:

  1. Run the following command to establish connection to OpenSearch from your local workspace in a separate terminal window. The command can be found as output named accessOpenSearchClusterOutput.
    • For Mac/Linux, use the following command:
aws ssm start-session --target <BastionHostId> --document-name AWS-StartPortForwardingSessionToRemoteHost --parameters '{"portNumber":["443"],"localPortNumber":["8157"], "host":["<OpenSearchDomainHost>"]}'
    • For Windows, use the following command:
aws ssm start-session ^
    —target <BastionHostId> ^
    —document-name AWS-StartPortForwardingSessionToRemoteHost ^    
    —parameters host="<OpenSearchDomainHost>",portNumber="443",localPortNumber="8157"

It should look similar to the following output:

Session Manager CLI

  1. Create the required index in OpenSearch by issuing the following command:
    • For Mac/Linux, use the following command:
curl --location -k --request PUT https://localhost:8157/processed_reviews \
--header 'Content-Type: application/json' \
--data-raw '{
  "mappings": {
    "properties": {
        "reviewId": {"type": "integer"},
        "userId": {"type": "keyword"},
        "summary": {"type": "keyword"},
        "sentiment": {"type": "keyword"},
        "dateTime": {"type": "date"}}}}}'
    • For Windows, use the following command:
$url = https://localhost:8157/processed_reviews
$headers = @{
    "Content-Type" = "application/json"
}
$body = @{
    "mappings" = @{
        "properties" = @{
            "reviewId" = @{ "type" = "integer" }
            "userId" = @{ "type" = "keyword" }
            "summary" = @{ "type" = "keyword" }
            "sentiment" = @{ "type" = "keyword" }
            "dateTime" = @{ "type" = "date" }
        }
    }
} | ConvertTo-Json -Depth 3
Invoke-RestMethod -Method Put -Uri $url -Headers $headers -Body $body -SkipCertificateCheck
  1. After the session is established, you can open your browser and navigate to https://localhost:8157/_dashboards. Your browser might consider the URL not secure. You can ignore this warning.
  2. Choose Dashboards Management under Management in the navigation pane.
  3. Choose Saved objects in the sidebar.
  4. Import export.ndjson, which can be found in the resources folder within the downloaded repository.

OpenSearch Dashboards Upload

  1. After you import the saved objects, you can navigate to Dashboards under My Dashboard in the navigation pane.

At the moment, the dashboard appears blank because you haven’t uploaded any review data to OpenSearch yet.

Set up the streaming producer

Finally, you can set up the producer that will be streaming review data to the Kinesis Data Stream and ultimately to the OpenSearch Dashboards. The Large Movie Review Dataset was originally published in 2011 in the paper “Learning Word Vectors for Sentiment Analysis” by Andrew L. Maas, Raymond E. Daly, Peter T. Pham, Dan Huang, Andrew Y. Ng, and Christopher Potts. Complete the following steps:

  1. Download the Large Movie Review Dataset here.
  2. After the download is complete, extract the .tar.gz file to retrieve the folder named aclImdb 3 or similar that contains the review data. Rename the review data folder to aclImdb.
  3. Move the extracted dataset to data/ inside the repository that you previously downloaded.

Your repository should look like the following screenshot.

Folder Overview

  1. Modify the DATA_DIR path in producer/producer.py if the review data is named differently.
  2. Move to the producer directory using the following command:
    cd producer

  3. Install the required dependencies and start generating the data:
    pip install -r requirements.txt && python produce.py

The OpenSearch dashboard should be populated after you start generating streaming data and writing it to the Kinesis Data Stream. Refresh the dashboard to view the latest data. The dashboard shows the total number of processed reviews, the sentiment distribution of the processed reviews in a pie chart, and the summary and sentiment for the latest reviews that have been processed.

When you have a closer look at the Flink application, you will notice that the application marks the sentiment field with the value error whenever there is an error with the asynchronous call made by Flink to the Amazon Bedrock API. The Flink application simply filters the correctly processed reviews and writes them to the OpenSearch dashboard.

For robust error handling, you should write any incorrectly processed reviews to a separate output stream and not discard them completely. This separation allows you to handle failed reviews differently than successful ones for simpler reprocessing, analysis, and troubleshooting.

Clean up

When you’re done with the resources you created, complete the following steps:

  1. Delete the Python producer using Ctrl/Command + C.
  2. Destroy your AWS CDK stack by returning to the root folder and running the following command in your terminal:
    cd cdk && cdk destroy

  3. When asked to confirm the deletion of the stack, enter yes.

Conclusion

In this post, you learned how to incorporate generative AI capabilities in your streaming architecture using Amazon Bedrock and Managed Service for Apache Flink using asynchronous requests. We also gave guidance on prompt engineering to derive the sentiment from text data using generative AI. You can build this architecture by deploying the sample code from the GitHub repository.

For more information on how to get started with Managed Service for Apache Flink, refer to Getting started with Amazon Managed Service for Apache Flink (DataStream API). For details on how to set up Amazon Bedrock, refer to Set up Amazon Bedrock. For other posts on Managed Service for Apache Flink, browse through the AWS Big Data Blog.


About the Authors

Felix John is a Solutions Architect and data streaming expert at AWS, based in Germany. He focuses on supporting small and medium businesses on their cloud journey. Outside of his professional life, Felix enjoys playing Floorball and hiking in the mountains.

Michelle Mei-Li Pfister is a Solutions Architect at AWS. She is supporting customers in retail and consumer packaged goods (CPG) industry on their cloud journey. She is passionate about topics around data and machine learning.

Uncover social media insights in real time using Amazon Managed Service for Apache Flink and Amazon Bedrock

Post Syndicated from Francisco Morillo original https://aws.amazon.com/blogs/big-data/uncover-social-media-insights-in-real-time-using-amazon-managed-service-for-apache-flink-and-amazon-bedrock/

With over 550 million active users, X (formerly known as Twitter) has become a useful tool for understanding public opinion, identifying sentiment, and spotting emerging trends. In an environment where over 500 million tweets are sent each day, it’s crucial for brands to effectively analyze and interpret the data to maximize their return on investment (ROI), which is where real-time insights play an essential role.

Amazon Managed Service for Apache Flink helps you to transform and analyze streaming data in real time with Apache Flink. Apache Flink supports stateful computation over a large volume of data in real time with exactly-once consistency guarantees. Moreover, Apache Flink’s support for fine-grained control of time with highly customizable window logic enables the implementation of the advanced business logic required for building a streaming data platform. Stream processing and generative artificial intelligence (AI) have emerged as powerful tools to harness the potential of real time data. Amazon Bedrock, along with foundation models (FMs) such as Anthropic Claude on Amazon Bedrock, empowers a new wave of AI adoption by enabling natural language conversational experiences.

In this post, we explore how to combine real-time analytics with the capabilities of generative AI and use state-of-the-art natural language processing (NLP) models to analyze tweets through queries related to your brand, product, or topic of choice. It goes beyond basic sentiment analysis and allows companies to provide actionable insights that can be used immediately to enhance customer experience. These include:

  • Identifying rising trends and discussion topics related to your brand
  • Conducting granular sentiment analysis to truly understand customers’ opinions
  • Detecting nuances such as emojis, acronyms, sarcasm, and irony
  • Spotting and addressing concerns proactively before they spread
  • Guiding product development based on feature requests and feedback
  • Creating targeted customer segments for information campaigns

This post takes a step-by-step approach to showcase how you can use Retrieval Augmented Generation (RAG) to reference real-time tweets as a context for large language models (LLMs). RAG is the process of optimizing the output of an LLM so it references an authoritative knowledge base outside of its training data sources before generating a response. LLMs are trained on vast volumes of data and use billions of parameters to generate original output for tasks such as answering questions, translating languages, and completing sentences. RAG extends the already powerful capabilities of LLMs to specific domains or an organization’s internal knowledge base, all without the need to retrain the model. It’s a cost-effective approach to improving LLM output so it remains relevant, accurate, and useful in various contexts.

Solution overview

In this section, we explain the flow and architecture of the application. We divide the flow of the application into two parts:

  • Data ingestion – Ingest data from streaming sources, convert it to vector embeddings, and then store them in a vector database
  • Insights retrieval – Invoke an LLM with the user queries to retrieve insights on tweets using the RAG technique

Data ingestion

The following diagram describes the data ingestion flow:

  1. Process feeds from streaming sources, such as social media feeds, Amazon Kinesis Data Streams, or Amazon Managed Service for Apache Kafka (Amazon MSK).
  2. Convert streaming data to vector embeddings in real time.
  3. Store them in a vector database.

Data is ingested from a streaming source (for example, X) and processed using an Apache Flink application. Apache Flink is an open source stream processing framework. It provides powerful streaming capabilities, enabling real-time processing, stateful computations, fault tolerance, high throughput, and low latency. Apache Flink is used to process the streaming data, perform deduplication, and invoke an embedding model to create vector embeddings.

Vector embeddings are numerical representations that capture the relationships and meaning of words, sentences, and other data types. These vector embeddings will be used for semantic search or neural search to retrieve relevant information that will be used as context for the LLM to evaluate the response. After the text data is converted into vectors, the vectors are persisted in an Amazon OpenSearch Service domain, which will be used as a vector database. Unlike traditional relational databases with rows and columns, data points in a vector database are represented by vectors with a fixed number of dimensions, which are clustered based on similarity.

OpenSearch Service offers scalable and efficient similarity search capabilities tailored for handling large volumes of dense vector data. OpenSearch Service seamlessly integrates with other AWS services, enabling you to build robust data pipelines within AWS. As a fully managed service, OpenSearch Service alleviates the operational overhead of managing the underlying infrastructure, while providing essential features like approximate k-Nearest Neighbor (k-NN) search algorithms, dense vector support, and robust monitoring and logging tools through Amazon CloudWatch. These capabilities make OpenSearch Service a suitable solution for applications that require fast and accurate similarity-based retrieval tasks using vector embeddings.

This design enables real-time vector embedding, making it ideal for AI-driven applications.

Insights retrieval

The following diagram shows the flow from the user side, where the user places a query through the frontend and gets a response from the LLM model using the retrieved vector database documents as the context provided in the prompt.

As shown in the preceding figure, to retrieve insights from the LLM, first you need to receive a query from the user. The text query is then converted into vector embeddings using the same model that was used before for the tweets. It’s important to make sure the same embedding model is used for both ingestion and search. The vector embeddings are then used to perform a semantic search in the vector database to obtain the related vectors and associated text. This serves as the context for the prompt. Next, the previous conversation history (if any) is added to the prompt. This serves as the conversation history for the model. Finally, the user’s question is also included in the prompt and the LLM is invoked to get the response.

For the purpose of this post, we don’t take into consideration the conversation history or store it for later use.

Solution architecture

Now that you understand the overall process flow, let’s analyze the following architecture using AWS services step by step.

The first part of the preceding figure shows the data ingestion process:

  1. A user authenticates with Amazon Cognito.
  2. The user connects to the Streamlit frontend and configures the following parameters: query terms, API bearer token, and frequency to retrieve tweets.
  3. Managed Service for Apache Flink is used to consume and process the tweets in real time and stores in Apache Flink’s state the parameters for making the API requests received from the frontend application.
  4. The streaming application uses Apache Flink’s async I/O to invoke the Amazon Titan Embeddings model through the Amazon Bedrock API.
  5. Amazon Bedrock returns a vector embedding for each tweet.
  6. The Apache Flink application then writes the vector embedding with the original text of the tweet into an OpenSearch Service k-NN index.

The remainder of the architecture diagram shows the insights retrieval process:

  1. A user sends a query through the Streamlit frontend application.
  2. An AWS Lambda function is invoked by Amazon API Gateway, passing the user query as input.
  3. The Lambda function uses LangChain to orchestrate the RAG process. As a first step, the function invokes the Amazon Titan Embeddings model on Amazon Bedrock to create a vector embedding for the question.
  4. Amazon Bedrock returns the vector embedding for the question.
  5. As a second step in the RAG orchestration process, the Lambda function performs a semantic search in OpenSearch Service and retrieves the relevant documents related to the question.
  6. OpenSearch Service returns the relevant documents containing the tweet text to the Lambda function.
  7. As a last step in the LangChain orchestration process, the Lambda function augments the prompt, adding the context and using few-shot prompting. The augmented prompt, including instructions, examples, context, and query, is sent to the Anthropic Claude model through the Amazon Bedrock API.
  8. Amazon Bedrock returns the answer to the question in natural language to the Lambda function.
  9. The response is sent back to the user through API Gateway.
  10. API Gateway provides the response to the user question in the Streamlit application.

The solution is available in the GitHub repo. Follow the README file to deploy the solution.

Now that you understand the overall flow and architecture, let’s dive deeper into some of the key steps to understand how it works.

Amazon Bedrock chatbot UI

The Amazon Bedrock chatbot Streamlit application is designed to provide insights from tweets, whether they are real tweets ingested from the X API or simulated tweets or messages from the My Social Media application.

In the Streamlit application, we can provide the parameters that will be used to make the API requests to the X Developer API and pull the data from X. We developed an Apache Flink application that adjusts the API requests based on the provided parameters.

As parameters, you need to provide the following:

  • Bearer token for API authorization – This is obtained from the X Developer platform when you sign up to use the APIs.
  • Query terms to be used to filter the tweets consumed – You can use the search operators available in the X documentation.
  • Frequency of the request – The X basic API only allows you to make a request every 15 seconds. If a lower interval is set, the application won’t pull data.

The parameters are sent to Kinesis Data Streams through API Gateway and are consumed by the Apache Flink application.

My Social Media UI

The My Social Media application is a Streamlit application that serves as an additional UI. Through this application, users can compose and send messages, simulating the experience of posting on a social media site. These messages are then ingested into an AWS data pipeline consisting of API Gateway, Kinesis Data Streams, and an Apache Flink application. The Apache Flink application processes the incoming messages, invokes an Amazon Bedrock embedding model, and stores the data in an OpenSearch Service cluster.

To accommodate both real X data and simulated data from the My Social Media application, we’ve set up separate indexes within the OpenSearch Service cluster. This separation allows users to choose which data source they want to analyze or query. The Streamlit application features a sidebar option called Use X Index that acts as a toggle. When this option is enabled, the application queries and analyzes data from the index containing real tweets ingested from the X API. If the option is disabled, the application queries and displays data from the index containing messages sent through the My Social Media application.

Apache Flink is used because of its ability to scale with the increasing volume of tweets. The Apache Flink application is responsible for performing data ingestion as explained previously. Let’s dive into the details of the flow.

Consume data from X

We use Apache Flink to process the API parameters sent from the Streamlit UI. We store the parameters in Apache Flink’s state, which allows us to modify and update the parameters without having to restart the application. We use the ProcessFunction to use Apache Flink’s internal timers to schedule the frequency of requests to fetch tweets. In this post, we use X’s Recent search API, which allows us to access filtered public tweets posted over the last 7 days. The API response is paginated and returns a maximum of 100 tweets on each request in reverse chronological order. If there are more tweets to be consumed, the response of the previous request will return a token, which needs to be used in the next API call. After we receive the tweets from the API, we apply the following transformations:

  • Filter out the empty tweets (tweets without any text).
  • Partition the set of tweets by author ID. This helps distribute the processing to multiple subtasks in Apache Flink.
  • Apply a deduplication logic to only process tweets that haven’t been processed. For this, we store the already processed tweet ID in Apache Flink’s state and match and filter out the tweets that have already been processed. We store the tweets’ ID grouped by author ID, which can cause the state size of the application to increase. Because the API only provides tweets from the last 7 days when invoked, we have introduced a time-to-live (TTL) of 7 days so we don’t grow the application’s state indefinitely. You can modify this based on your requirements.
  • Convert tweets into JSON objects for a later Amazon Bedrock API invocation.

Create vector embeddings

The vector embeddings are created by invoking the Amazon Titan Embeddings model through the Amazon Bedrock API. Asynchronous invocations of external APIs are important performance considerations when building a stream processing architecture. Synchronous calls increase latency, reduce throughput, and can be a bottleneck for overall processing.

To invoke the Amazon Bedrock API, you will use the Amazon Bedrock Runtime dependency in Java, which provides an asynchronous client that allows us invoke Amazon Bedrock models asynchronously through the BedrockRuntimeAsyncClient. This is invoked to create the embeddings. For this we use Apache Flink’s async I/O to make asynchronous requests to external APIs. Apache Flink’s async I/O is a library within Apache Flink that allows you to write asynchronous, non-blocking operators for stream processing applications, enabling better utilization of resources and higher throughput. We provide the asynchronous function to be called, the timeout duration that determines how long an asynchronous operation can take before it’s considered failed, and the maximum number of requests that should be in progress at any point in time. Limiting the number of concurrent requests makes sure that the operator won’t accumulate an ever-growing backlog of pending requests. However, this can cause backpressure after the capacity is exhausted. Because we use the timestamp of creation when we ingest into OpenSearch Service and so order won’t affect our results, we can use Apache Flink’s async I/O unordered function, allowing us to have better throughput and performance. See the following code:

DataStream<JSONObject> resultStream = AsyncDataStream

.unorderedWait(inputJSON, new BedRockEmbeddingModelAsyncTweetFunction(), 15000, TimeUnit.MILLISECONDS, 1000)
.uid("tweet-async-function");

Let’s have a closer look into the Apache Flink async I/O function. The following is within the CompletableFuture Java class:

  1. First, we create the Amazon Bedrock Runtime async client:
BedrockRuntimeAsyncClient runtime = BedrockRuntimeAsyncClient.builder()
.region(Region.of(region))  // Use the specified AWS region 
.build();
  1. We then extract the tweet for the event and build the payload that we will send to Amazon Bedrock:
String stringBody = jsonObject.getString("tweet");

ArrayList<String> stringList = new ArrayList<>();


stringList.add(stringBody);


JSONObject jsonBody = new JSONObject()
.put("inputText", stringBody);


SdkBytes body = SdkBytes.fromUtf8String(jsonBody.toString());
  1. After we have the payload, we can call the InvokeModel API and invoke Amazon Titan to create the vector embeddings for the tweets:
InvokeModelRequest request = InvokeModelRequest.builder()
        
.modelId("amazon.titan-embed-text-v1")
        
.contentType("application/json")
        
.accept("*/*")
        
.body(body)
        
.build();

CompletableFuture<InvokeModelResponse> futureResponse = runtime.invokeModel(request);
  1. After receiving the vector, we append the following fields to the output JSONObject:
    1. Cleaned tweet
    2. Tweet creation timestamp
    3. Number of likes of the tweet
    4. Number of retweets
    5. Number of views from the tweet (impressions)
    6. Tweet ID
// Extract and process the response when it is available
JSONObject response = new JSONObject(
        futureResponse.join().body().asString(StandardCharsets.UTF_8)
);

// Add additional fields related to tweet data to the response
response.put("tweet", jsonObject.get("tweet"));
response.put("@timestamp", jsonObject.get("created_at"));
response.put("likes", jsonObject.get("likes"));
response.put("retweet_count", jsonObject.get("retweet_count"));
response.put("impression_count", jsonObject.get("impression_count"));
response.put("_id", jsonObject.get("_id"));

return response;

This will return the embeddings, original text, additional fields, and the number of tokens used for the embedding. In our connector, we are only consuming messages in English, as well as ignoring messages that are retweets from other tweets.

The same processing steps are replicated for messages coming from the My Social Media application (manually ingested).

Store vector embeddings in OpenSearch Service

We use OpenSearch Service as a vector database for semantic search. Before we can write the data into OpenSearch Service, we need to create an index that supports semantic search. We are using the k-NN plugin. The vector database index mapping should have the following properties for storing vectors for similarity search:

…

"embeddings": {
        "type": "knn_vector",
        "dimension": 1536,
        "method": {
          "name": "hnsw",
          "space_type": "l2",
          "engine": "nmslib",
          "parameters": {
            "ef_construction": 128,
            "m": 24
          }
        }
      }

…

The key parameters are as follows:

  • type – This specifies that the field will hold vector data for a k-NN similarity search. The value should be knn_vector.
  • dimension – The number of dimensions for each vector. This must match the model dimension. In this case we use 1,536 dimensions, the same as the Amazon Titan Text Embeddings v1 model.
  • method – Defines the algorithm and parameters for indexing and searching the vectors:
    • name – The identifier for the nearest neighbor method. We use hierarchical navigable small worlds (HNSW)—a hierarchical proximity graph approach—to run a approximate k-NN (A-NN) search because standard k-NN is not a scalable approach.
    • space_type – The vector space used to calculate the distance between vectors. It supports multiple space type. The default value is 12.
    • engine – The approximate k-NN library to use for indexing and search. The available libraries are faiss, nmslib, and Lucene.
    • ef_construction – The size of the dynamic list used during k-NN graph creation. Higher values result in a more accurate graph but slower indexing speed.
    • m – The number of bidirectional links that the plugin creates for each new element. Increasing and decreasing this value can have a large impact on memory consumption. Keep this value between 2–100.

Standard k-NN search methods compute similarity using a brute-force approach that measures the nearest distance between a query and a number of points, which produces exact results. This works well for most applications. However, in the case of extremely large datasets with high dimensionality, this creates a scaling problem that reduces the efficiency of the search. The approximate k-NN search methods used by OpenSearch Service use approximate nearest neighbor (ANN) algorithms from the nmslib, faiss, and Lucene libraries to power k-NN search. These search methods employ ANN to improve search latency for large datasets. Of the three search methods the k-NN plugin provides, this method offers the best search scalability for large datasets. This approach is the preferred method when a dataset reaches hundreds of thousands of vectors. For more information about the different methods and their trade-offs, refer to Comprehensive Guide To Approximate Nearest Neighbors Algorithms.

To use the k-NN plugin’s approximate search functionality, we must first create a k-NN index with index.knn set to true:

    "settings" : {
      "index" : {
        "knn": true,
        "number_of_shards" : "5",
        "number_of_replicas" : "1"
      }
    }

After we have our indexes created, we can sink the data from our Apache Flink application into OpenSearch.

RetrievalQA using Lambda and LangChain implementation

For this part, we take an input question from the user and invoke a Lambda function. The Lambda function retrieves relevant tweets from OpenSearch Service as context and generates an answer using the LangChain RAG chain RetrievalQA. LangChain is a framework for developing applications powered by language models.

First, some setup. We instantiate the bedrock-runtime client that will allow the Lambda function to invoke the models:

bedrock_runtime = boto3.client("bedrock-runtime", "us-east-1")

embeddings = BedrockEmbeddings(model_id="amazon.titan-embed-text-v1", client=bedrock_runtime)

The BedrockEmbeddings class uses the Amazon Bedrock API to generate embeddings for the user’s input question. It strips new line characters from the text. Notice that we need to pass as an argument the instantiation of the bedrock_runtime client and the model ID for the Amazon Titan Text Embeddings v1 model.

Next, we instantiate the client for the OpenSearchVectorSeach LangChain class that will allow the Lambda function to connect to the OpenSearch Service domain and perform the semantic search against the previously indexed X embeddings. For the embedding function, we’re passing the embeddings model that we defined previously. This will be used during the LangChain orchestration process:

os_client = OpenSearchVectorSearch(
        index_name=aos_index,
        embedding_function=embeddings,
        http_auth=(os.environ['aosUser'], os.environ['aosPassword']),
        opensearch_url=os.environ['aosDomain'],
        timeout=300,
        use_ssl=True,
        verify_certs=True,
        connection_class=RequestsHttpConnection,
        )

We need to define the LLM model from Amazon Bedrock to use for text generation. The temperature is set to 0 to reduce hallucinations:

model_kwargs={"temperature": 0, "max_tokens": 4096}

llm = BedrockChat(
    model_id="anthropic.claude-3-haiku-20240307-v1:0",
    client=bedrock_runtime,
    model_kwargs=model_kwargs
)

Next, in our Lambda function, we create the prompt to instruct the model on the specific task of analyzing hundreds of tweets in the context. To normalize the output, we use a prompt engineering technique called few-shot prompting. Few-shot prompting allows language models to learn and generate responses based on a small number of examples or demonstrations provided in the prompt itself. In this approach, instead of training the model on a large dataset, we provide a few examples of the desired task or output within the prompt. These examples serve as a guide or conditioning for the model, enabling it to understand the context and the desired format or pattern of the response. When presented with a new input after the examples, the model can then generate an appropriate response by following the patterns and context established by the few-shot demonstrations in the prompt.

As part of the prompt, we then provide examples of questions and answers, so the chatbot can follow the same pattern when used (see the Lambda function to view the complete prompt):

template = """As a helpful agent that is an expert analysing tweets, please answer the question using only the provided tweets from the context in <context></context> tags. If you don't see valuable information on the tweets provided in the context in <context></context> tags, say you don't have enough tweets related to the question. Cite the relevant context you used to build your answer. Print in a bullet point list the top most influential tweets from the context at the end of the response.
    
    Find below some examples:
    <example1>
    question: 
    What are the main challenges or concerns mentioned in tweets about using Bedrock as a generative AI service on AWS, and how can they be addressed?
    
    answer:
    Based on the tweets provided in the context, the main challenges or concerns mentioned about using Bedrock as a generative AI service on AWS are:

1.	...
2.	...
3.	...
4.	...
...
    
    To address these concerns:

1.	...
2.	...
3.	...
4.	...
...

    Top tweets from context:

    [1] ...
    [2] ...
    [3] ...
    [4] ...

    </example1>
    
    <example2>
    ...
    </example2>
    
    Human: 
    
    question: {question}
    
    <context>
    {context}
    </context>
    
    Assistant:"""

    prompt = PromptTemplate(input_variables=["context","question"], template=template)

We then create the RetrievalQA LangChain chain using the prompt template, Anthropic Claude on Amazon Bedrock, and the OpenSearch Service retriever configured previously. The RetrievalQA LangChain chain will orchestrate the following RAG steps:

  • Invoke the text embedding model to create a vector for the user’s question
  • Perform a semantic search on OpenSearch Service using the vector to retrieve the relevant tweets to the user’s question (k=200)
  • Invoke the LLM model using the augmented prompt containing the prompt template, context (stuffed retrieved tweets) and question
chain = RetrievalQA.from_chain_type(
    llm=llm,
    verbose=True,
    chain_type="stuff",
    retriever=os_client.as_retriever(
        search_type="similarity",
        search_kwargs={
            "k": 200, 
            "space_type": "l2", 
            "vector_field": "embeddings", 
            "text_field": text_field
        }
    ),
    chain_type_kwargs = {"prompt": prompt}
)

Finally, we run the chain:

answer = chain.invoke({"query": message})

The response from the LLM is sent back to the user application. As shown in the following screenshot:

Considerations

You can extend the solution provided in this post. When you do, consider the following suggestions:

  • Configure index retention and rollover in OpenSearch Service to manage index lifecycle and data retention effectively
  • Incorporate chat history into the chatbot to provide richer context and improve the relevance of LLM responses
  • Add filters and hybrid search with the possibility to modify the weight given to the keyword and semantic search to enhance search on RAG
  • Modify the TTL for Apache Flink’s state to match your requirements (the solution in this post uses 7 days)
  • Enable logging to API Gateway and in the Streamlit application.

Summary

This post demonstrates how to combine real-time analytics with generative AI capabilities to analyze tweets related to a brand, product, or topic of interest. It uses Amazon Managed Service for Apache Flink to process tweets from the X API, create vector embeddings using the Amazon Titan Embeddings model on Amazon Bedrock, and store the embeddings in an OpenSearch Service index configured for vector similarity search—all these steps happen in real time.

The post also explains how users can input queries through a Streamlit frontend application, which invokes a Lambda function. This Lambda function retrieves relevant tweets from OpenSearch Service by performing semantic search on the stored embeddings using the LangChain RetrievalQA chain. As a result, it generates insightful answers using the Anthropic Claude LLM on Amazon Bedrock.

The solution enables identifying trends, conducting sentiment analysis, detecting nuances, addressing concerns, guiding product development, and creating targeted customer segments based on real-time X data.

To get started with generative AI, visit Generative AI on AWS for information about industry use cases, tools to build and scale generative AI applications, as well as the post Exploring real-time streaming for generative AI Applications for other use cases for streaming with generative AI.


About the Authors

Francisco Morillo is a Streaming Solutions Architect at AWS, specializing in real-time analytics architectures. With over five years in the streaming data space, Francisco has worked as a data analyst for startups and as a big data engineer for consultancies, building streaming data pipelines. He has deep expertise in Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink. Francisco collaborates closely with AWS customers to build scalable streaming data solutions and advanced streaming data lakes, ensuring seamless data processing and real-time insights.

Sergio Garcés Vitale is a Senior Solutions Architect at AWS, passionate about generative AI. With over 10 years of experience in the telecommunications industry, where he helped build data and observability platforms, Sergio now focuses on guiding Retail and CPG customers in their cloud adoption, as well as customers across all industries and sizes in implementing Artificial Intelligence use cases.
Subham Rakshit is a Streaming Specialist Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughter.

Anthropic’s Claude 3.5 Sonnet model now available in Amazon Bedrock: Even more intelligence than Claude 3 Opus at one-fifth the cost

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/anthropics-claude-3-5-sonnet-model-now-available-in-amazon-bedrock-the-most-intelligent-claude-model-yet/

It’s been just 3 months since Anthropic launched Claude 3, a family of state-of-the-art artificial intelligence (AI) models that allows you to choose the right combination of intelligence, speed, and cost that suits your needs.

Today, Anthropic introduced Claude 3.5 Sonnet, its first release in the forthcoming Claude 3.5 model family. We are happy to announce that Claude 3.5 Sonnet is now available in Amazon Bedrock.

Claude 3.5 Sonnet raises the industry bar for intelligence, outperforming other generative AI models on a wide range of evaluations, including Anthropic’s previously most intelligent model, Claude 3 Opus. Claude 3.5 Sonnet is available with the speed and cost of the original Claude 3 Sonnet model. In fact, you can now get intelligence and speed better than Claude 3 Opus at one-fifth of the price because Claude 3.5 Sonnet is 80 percent cheaper than Opus.

Anthropic Claude 3.5 Sonnet Family

The frontier intelligence displayed by Claude 3.5 Sonnet combined with cost-effective pricing, makes the model ideal for complex tasks such as context-sensitive customer support, orchestrating multi-step workflows, and streamlining code translations.

Claude 3.5 Sonnet sets new industry benchmarks for undergraduate-level expert knowledge (MMLU), graduate-level expert reasoning (GPQA), code (HumanEval), and more. As you can see in the following table, according to Anthropic, Claude 3.5 Sonnet outperforms OpenAI’s GPT-4o and Google’s Gemini 1.5 Pro in nearly every benchmark.

Anthropic Claude 3.5 Sonnet Benchmarks

Claude 3.5 Sonnet is also Anthropic’s strongest vision model yet, performing an average of 10 percent better than Claude 3 Opus across the majority of vision benchmarks. According to Anthropic, Claude 3.5 Sonnet also outperforms other generative AI models in nearly every category.

Anthropic Claude 3.5 Sonnet Vision Benchmarks

Anthropic’s Claude 3.5 Sonnet key improvements
The release of Claude 3.5 Sonnet brings significant improvements across multiple domains, empowering software developers and businesses with new generative AI-powered capabilities. Here are some of the key strengths of this new model:

Visual processing and understanding – Claude 3.5 Sonnet demonstrates remarkable capabilities in processing images, particularly in interpreting charts and graphs. It accurately transcribes text from imperfect images, a core capability for industries such as retail, logistics, and financial services, to gather more insights from graphics or illustrations than from text alone. Use Claude 3.5 Sonnet to automate visual data processing tasks, extract valuable information, and enhance data analysis pipelines.

Writing and content generation – Claude 3.5 Sonnet represents a significant leap in its ability to understand nuance and humor. The model produces high-quality written content with a more natural, human tone that feels more authentic and relatable. Use the model to generate engaging and compelling content, streamline your writing workflows, and enhance your storytelling capabilities.

Customer support and natural language processing – With its improved understanding of context and multistep workflow orchestration, Claude 3.5 Sonnet excels at handling intricate customer inquiries. This capability enables round-the-clock support, faster response times, and more natural-sounding interactions, ultimately leading to improved customer satisfaction. Use this model to automate and enhance customer support processes and provide a seamless experience for end users. For an example of a similar implementation, see how DoorDash built a generative AI self-service contact center solution using Anthropic’s Claude 3 models in Amazon Bedrock.

Analytics and insights – Claude 3.5 Sonnet augments human expertise in data science by effortlessly navigating unstructured data and using multiple tools to generate insights. It produces high-quality statistical visualizations and actionable predictions, ranging from business strategies to real-time product trends. Use Claude 3.5 Sonnet to simplify data analysis workflows, uncover valuable insights, and drive data-driven decision-making.

Coding and software development – Claude 3.5 Sonnet can independently write, edit, and execute code with sophisticated reasoning and troubleshooting capabilities when provided with the relevant tools. Use Claude 3.5 Sonnet to streamline developer workflows, accelerate coding tasks, reduce manual effort, and enhance overall productivity.

Using Anthropic’s Claude 3.5 Sonnet in the Amazon Bedrock console
Because this is a new model, I go to the Amazon Bedrock console and choose Model access from the navigation pane to enable access to Claude 3.5 Sonnet.

Console screenshot.

Now that I have access to the model, I’d like to use it to extract information from the following image from the Our World in Data website:

Primary energy consumption from hydropower, 2022

I choose Chat in the Playgrounds section of the navigation pane and select Anthropic and Claude 3.5 Sonnet as the model. I then choose the Image upload button to upload the previous image, type the following prompt, and choose Run:

Which countries consume more than 1000 TWh from hydropower? Think step by step and look at all regions. Output in JSON.

Here’s the result and an animated image recapping what I did.

To determine which countries consume more than 1,000 TWh from hydropower in 2022, I need to carefully examine the map and color-coding. The scale at the bottom shows that dark blue represents consumption between 1,000 TWh and 2,000 TWh.

Let's look at each region systematically:

1. North America: Canada is dark blue, indicating it consumes between 1,000-2,000 TWh from hydropower.
2. South America: Brazil is dark blue, also consuming between 1,000-2,000 TWh.
3. Europe: No country is dark blue; all are light green or have no data.
4. Africa: No data available for any country.
5. Asia: China is dark blue, indicating consumption between 1,000-2,000 TWh.
6. Oceania: No country is dark blue; Australia is light green.

In summary, there are three countries that consume more than 1,000 TWh from hydropower in 2022:
1. Canada (North America)
2. Brazil (South America)
3. China (Asia)

Here's the response in JSON format:

```json
{
  "countries_consuming_over_1000TWh_hydropower": [
    {
      "name": "Canada",
      "region": "North America",
      "consumption_range": "1,000-2,000 TWh"
    },
    {
      "name": "Brazil",
      "region": "South America",
      "consumption_range": "1,000-2,000 TWh"
    },
    {
      "name": "China",
      "region": "Asia",
      "consumption_range": "1,000-2,000 TWh"
    }
  ]
}
```

These three countries stand out as the highest consumers of hydropower energy, each using between 1,000 and 2,000 terawatt-hours in 2022.

Anthropic's Claude 3.5 Sonnet demo in the Amazon Bedrock console.

The model’s ability to reliably extract information from unstructured data, like images, opens up a world of new possibilities.

I choose the three small dots in the corner of the playground window and then View API request to see code examples using the model in the AWS Command Line Interface (AWS CLI) and AWS SDKs. Let’s have a better look at the code syntax.

Using Claude 3.5 Sonnet with AWS SDKs
You can use Claude 3.5 Sonnet with any AWS SDK using the new Amazon Bedrock Converse API or Anthropic Claude Messages API.

To update code already using a Claude 3 model, I just need to replace the model ID with:

anthropic.claude-3-5-sonnet-20240620-v1:0

Here’s a sample implementation with the AWS SDK for Python (Boto3) using the same image as before to show how to use images and text with the Converse API.

import boto3
from botocore.exceptions import ClientError

MODEL_ID = "anthropic.claude-3-5-sonnet-20240620-v1:0"

IMAGE_NAME = "primary-energy-hydro.png"

bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")

with open(IMAGE_NAME, "rb") as f:
    image = f.read()

user_message = "Which countries consume more than 1000 TWh from hydropower? Think step by step and look at all regions. Output in JSON."

messages = [
    {
        "role": "user",
        "content": [
            {"image": {"format": "png", "source": {"bytes": image}}},
            {"text": user_message},
        ],
    }
]

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=messages,
)
response_text = response["output"]["message"]["content"][0]["text"]
print(response_text)

When I run it, I get a similar output as in the console:

Let's approach this step-by-step:

1. First, I'll examine the color scale at the bottom of the map. The darkest blue color represents consumption of 2,000 TWh or more.

2. Now, I'll scan the map region by region:

   North America: Canada is dark blue, indicating over 1,000 TWh.
   South America: Brazil is also dark blue, over 1,000 TWh.
   Europe: No country appears to be dark blue.
   Africa: No country appears to be dark blue.
   Asia: China stands out as dark blue, indicating over 1,000 TWh.
   Oceania: No country appears to be dark blue.

3. To be thorough, I'll double-check for any medium blue countries that might be close to or over 1,000 TWh, but I don't see any that appear to reach that threshold.

4. Based on this analysis, there are three countries that clearly consume more than 1,000 TWh from hydropower.

Now, I'll format the answer in JSON:

```json
{
  "countries_consuming_over_1000TWh_hydropower": [
    "Canada",
    "Brazil",
    "China"
  ]
}
```

This JSON output lists the three countries that visually appear to consume more than 1,000 TWh of primary energy from hydropower according to the 2022 data presented in the map.

Because I didn’t specify a JSON syntax, the two answers use a different format. In your applications, you can describe in the prompt the JSON properties you want or provide a sample to get a standard format in output.

For more examples, see the code samples in the Amazon Bedrock User Guide. For a more advanced use case, here’s a fully functional tool use demo illustrating how to connect a generative AI model with a custom tool or API.

Using Claude 3.5 Sonnet with the AWS CLI
There are times when nothing beats the speed of the command line. This is how you can use the AWS CLI with the new model:

aws bedrock-runtime converse \
    --model-id anthropic.claude-3-5-sonnet-20240620-v1:0 \
    --messages '{"role": "user", "content": [{"text": "Alice has N brothers and she also has M sisters. How many sisters does Alice’s brother have?"}]}' \
    --region us-east-1
    --query output.message.content

In the output, I use the query option to only get the content of the output message:

[
    {
        "text": "Let's approach this step-by-step:\n\n1. First, we need to understand the relationships:\n   - Alice has N brothers\n   - Alice has M sisters\n\n2. Now, let's consider Alice's brother:\n   - He is one of Alice's N brothers\n   - He has the same parents as Alice\n\n3. This means that Alice's brother has:\n   - The same sisters as Alice\n   - One sister more than Alice (because Alice herself is his sister)\n\n4. Therefore, the number of sisters Alice's brother has is:\n   M + 1\n\n   Where M is the number of sisters Alice has.\n\nSo, the answer is: Alice's brother has M + 1 sisters."
    }
]

I copy the text into a small Python program to see it printed on multiple lines:

print("Let's approach this step-by-step:\n\n1. First, we need to understand the relationships:\n   - Alice has N brothers\n   - Alice has M sisters\n\n2. Now, let's consider Alice's brother:\n   - He is one of Alice's N brothers\n   - He has the same parents as Alice\n\n3. This means that Alice's brother has:\n   - The same sisters as Alice\n   - One sister more than Alice (because Alice herself is his sister)\n\n4. Therefore, the number of sisters Alice's brother has is:\n   M + 1\n\n   Where M is the number of sisters Alice has.\n\nSo, the answer is: Alice's brother has M + 1 sisters.")
Let's approach this step-by-step:

1. First, we need to understand the relationships:
   - Alice has N brothers
   - Alice has M sisters

2. Now, let's consider Alice's brother:
   - He is one of Alice's N brothers
   - He has the same parents as Alice

3. This means that Alice's brother has:
   - The same sisters as Alice
   - One sister more than Alice (because Alice herself is his sister)

4. Therefore, the number of sisters Alice's brother has is:
   M + 1

   Where M is the number of sisters Alice has.

So, the answer is: Alice's brother has M + 1 sisters.

Even if this was a quite nuanced question, Claude 3.5 Sonnet got it right and described its reasoning step by step.

Things to know
Anthropic’s Claude 3.5 Sonnet is available in Amazon Bedrock today in the US East (N. Virginia) AWS Region. More information on Amazon Bedrock model support by Region is available in the documentation. View the Amazon Bedrock pricing page to determine the costs for your specific use case.

By providing access to a faster and more powerful model at a lower cost, Claude 3.5 Sonnet makes generative AI easier and more effective to use for many industries, such as:

Healthcare and life sciences – In the medical field, Claude 3.5 Sonnet shows promise in enhancing imaging analysis, acting as a diagnostic assistant for patient triage, and summarizing the latest research findings in an easy-to-digest format.

Financial services – The model can provide valuable assistance in identifying financial trends and creating personalized debt repayment plans tailored to clients’ unique situations.

Legal – Law firms can use the model to accelerate legal research by quickly surfacing relevant precedents and statutes. Additionally, the model can increase paralegal efficiency through contract analysis and assist with drafting standard legal documents.

Media and entertainment – The model can expedite research for journalists, support the creative process of scriptwriting and character development, and provide valuable audience sentiment analysis.

Technology – For software developers, Claude 3.5 Sonnet offers opportunities in rapid application prototyping, legacy code migration, innovative feature ideation, user experience optimization, and identification of friction points.

Education – Educators can use the model to streamline grant proposal writing, develop comprehensive curricula incorporating emerging trends, and receive research assistance through database queries and insight generation.

It’s an exciting time for for generative AI. To start using this new model, see the Anthropic Claude models section of the Amazon Bedrock User Guide. You can also visit our community.aws site to find deep-dive technical content and to discover how our Builder communities are using Amazon Bedrock in their solutions. Let me know what you do with these enhanced capabilities!

— Danilo

Three ways Amazon Q Developer agent for code transformation accelerates Java upgrades

Post Syndicated from Venugopalan Vasudevan original https://aws.amazon.com/blogs/devops/three-ways-amazon-q-developer-agent-for-code-transformation-accelerates-java-upgrades/

When Amazon Web Services (AWS) launched Amazon Q Developer agent for code transformation as a preview last year to upgrade Java applications, we saw many organizations desire to significantly accelerate their Java upgrades. Previously, these upgrades were considered daunting, a time-consuming manual task requiring weeks if not months of effort and with Amazon Q Developer they could significantly reduce that burden. Companies such as Toyota, Novacamp, Pragma and Persistent saw productivity gains not only in reducing the amount of time the upgrades would take, but re-prioritizing that time saved into other business priorities related to the software development lifecycle (SDLC). In addition, a small team of AWS developers upgraded over 1000 carefully chosen applications from multiple independent services. These applications used less than 10 dependencies and required minimal mandatory changes to the application code for the upgrade. While we saw a high degree of upgrade success for simpler applications, we also heard from customers who wanted even more capabilities in the Amazon Q Developer agent for code transformation. They expected the agent to upgrade their libraries to the latest major versions, replace deprecated API calls, and provide more explainability of changes made.

We added these and more capabilities to the agent at General Availability (GA). Today, we’re going into detail on the following four categories for what Amazon Q Developer can do for your Java upgrades: major version upgrades of popular frameworks, directly replacing deprecated API calls on your behalf, clear explainability on code changes, and using some examples of our unprecedented AI technology powered by Amazon Bedrock, that is capable, for example, of correcting more compilation errors that can be encountered when attempting the build in Java 17.

This blog post will dive deeper into these three ways we improved the product experience through an example application. You can download the application from this GitHub repository.

About the application

This is a Java 1.8 based microservice application which displays free list of movies for the month based on configuration stored in AWS AppConfig service using AWS SDK. This application was first open sourced in 2020 and uses legacy versions of libraries such as Spring Boot 2.x, Log4j 2.13.x, Mockito 1.x, Javax and Junit 4. You can download the sample project to try it for yourself.

(1) Popular framework upgrades

While Spring Boot version 2.7 is compatible with Java 17, Amazon Q Developer agent for code transformation can bring your applications up to version 3.2. This has been helpful because it can be time consuming to correct all the changes in annotations and code implementation that are no longer compatible when going into the new major version upgrade. Moreover, this version of Spring Boot provides improved observability, performance improvements, modernized security, and overall enhanced development experience. Let’s dive into some examples of where you see Amazon Q Developer accelerate some of this heavy lifting during the upgrade process.

When working with file uploads in Spring Boot v2, you would typically use the @RequestParam("file") annotation to bind the uploaded file to a method parameter. However, in Spring Boot v3.2, this approach has been updated to better align with the Jakarta EE specifications. Instead of using a plain String parameter, you’ll need to use the MultipartFile class from the org.springframework.web.multipart package. Here is an example before and after code transformation with Amazon Q Developer:

Java 8 code with Spring v2

@RequestMapping(value = "/movies/{movie}/edit", method = POST)
public String processUpdateMovie(@Valid Movie movie, BindingResult result, 
                           @PathVariable("movieId") int movieId) {
   
   ...
} 

Java 17 code upgraded by Amazon Q Developer with Spring v3

@PostMapping("/movies/{movie}/edit")
public String processUpdateMovie(@Valid Movie movie, BindingResult result,
                           @PathVariable int movieId) {

... 
}

Associated dependency updates in pom.xml

<parent>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-parent</artifactId>
    <version>2.0.5.RELEASE</version>
</parent>
to
<parent>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-parent</artifactId>
    <version>3.2.5</version>
</parent>

The following lists some common libraries we’ve seen you all use, with the corresponding compatible version in Java 8 and what we’re capable of upgrading to using Q Developer. This list isn’t comprehensive of all libraries, the intent is to show some common ones. This could change in the future and is up-to-date as of the time of this publication.

Table-QCT

Let’s review a few examples from the Sample project.

Java 8 code with Junit 4

import org.junit.Test;
import org.junit.runner.RunWith;
import org.springframework.boot.test.context.SpringBootTest;
import org.springframework.test.context.junit4.SpringRunner;
import com.amazonaws.samples.appconfig.movies.MoviesController;

@RunWith(SpringRunner.class)
@SpringBootTest
public class MovieTest {
  ...
}
@Before
public void setUp() {
    MockitoAnnotations.initMocks(this);
    moviesController = new MoviesController();
    moviesController.env = env;
}
<dependency>
    <groupId>junit</groupId>
    <artifactId>junit</artifactId>
    <version>4.13.1</version>
    <scope>test</scope>
</dependency>

Java 17 code upgraded by Amazon Q Developer with Junit 5:

import org.junit.jupiter.api.Test;
import org.springframework.boot.test.context.SpringBootTest;
import com.amazonaws.samples.appconfig.movies.MoviesController;

@SpringBootTest
public class MovieTest {
  ...
}
@BeforeEach
public void setUp() {
    MockitoAnnotations.initMocks(this);
    moviesController = new MoviesController();
    moviesController.env = env;
}
<dependency>
    <groupId>org.junit.jupiter</groupId>
    <artifactId>junit-jupiter</artifactId>
    <scope>test</scope>
</dependency>

(2) Deprecated APIs

One of the biggest challenges organizations face when upgrading to a newer version of Java is dealing with deprecated APIs. As new language features and libraries are introduced, older APIs are often marked as deprecated and eventually removed in subsequent releases. This can lead to compilation errors and compatibility issues, requiring developers to manually identify and replace these deprecated APIs throughout their codebase – a time-consuming and error-prone process.

In our sample application, you will see a variety of deprecated APIs that are addressed by Q Developer as an output of the transformation to Java 17. Here are some examples:

Before:

bd.divide(bd2, BigDecimal.ROUND_DOWN);
bd.divide(bd2, 1, BigDecimal.ROUND_CEILING);     

After:

bd.divide(bd2, RoundingMode.DOWN);
bd.divide(bd2, 1, RoundingMode.CEILING);

Before:

String enc1 = new sun.misc.BASE64Encoder().encode(bytes);

After:

import java.util.Base64;
String enc1 = Base64.getEncoder().encodeToString(bytes);

Before:

import javax.security.cert.*;

After:

import java.security.cert.*;

Before:

import static org.mockito.Matchers.anyInt;
...
when(mocklist.get(anyInt())).thenReturn("Movies");

After:

import static org.mockito.ArgumentMatchers.anyInt;
...
when(mocklist.get(anyInt())).thenReturn("Movies");

Java versions before 15 required explicit line terminators, string concatenations, and delimiters to embed multi-line code snippets. Java 15 introduced text blocks to simplify embedding code snippets and text sequences, particularly useful for literals like HTML, JSON, and SQL. Text blocks are an alternative string representation that can replace traditional double-quoted string literals, allowing multi-line strings without explicit line terminators or concatenations. Amazon Q Developer agent for code transformation will migrate your complex multi-line text which not so readable to text blocks.

Before:

private static String getMovieItemsHtml(Movie[] movies) {
        StringBuilder movieItemsHtml = new StringBuilder();
        for (Movie movie : movies) {
            movieItemsHtml.append("<div class='movie-item'>"
                    + "<p>ID: ").append(movie.getId()).append("</p>"
                    + "<h3>").append(movie.getMovieName()).append("</h3>"
                    + "<hr width=\"100%\" size=\"2\" color=\"blue\" noshade>"
                    + "</div>");
        }
        return movieItemsHtml.toString();
    }

After:

private static String getMovieItemsHtml(Movie[] movies) {
        StringBuilder movieItemsHtml = new StringBuilder();
        for (Movie movie : movies) {
            movieItemsHtml.append("""
                    <div class='movie-item'>\
                    <p>ID: \
                    """).append(movie.getId()).append("""
                    </p>\
                    <h3>\
                    """).append(movie.getMovieName()).append("""
                    </h3>\
                    <hr width="100%" size="2" color="blue" noshade>\
                    </div>\
                    """);
        }
        return movieItemsHtml.toString();
    }

Including these examples above in the sample app, Q Developer supports a wide range of abilities to address deprecated APIs across various domains, including primitive type constructors and conversions, character and string utilities, date and time handling, mathematical operations, networking and sockets, security and cryptography, concurrent programming and atomics, reflection and bytecode generation, as well as a significant number of deprecated methods related to Swing and AWT components. Whether it’s replacing outdated methods for handling dates, encoding URLs, or working with BigDecimal arithmetic, we can automatically update your code to use their modern equivalents. It also addresses deprecations in areas like multicast sockets, atomic variables, and even bytecode generation using ASM.

With the Q Developer agent for code transformation, we’ve made it easier than ever to handle deprecated APIs during your Java 17 migration. Q Developer is capable of automatically detecting and replacing deprecated API calls with their modern equivalents, saving you countless hours of manual effort and reducing the risk of introducing bugs or regressions.

(3) Unprecedented AI technology

Even after addressing deprecated APIs and framework upgrades, the process of migrating to a new Java version can still encounter compilation errors or unexpected behavior. These issues can arise from subtle changes in language semantics, incompatibilities between libraries, or other factors that are difficult to anticipate and diagnose.

To tackle this challenge, the Q Developer agent for code transformation leverages our self-debugging technology powered by Bedrock which analyzes the context of compilation errors and is capable of implementing targeted code modifications to resolve them. Here are some examples.

Java 1.8 with javax.security.X509Certificate:

import javax.security.cert.*;
import java.io.File;
import java.io.FileInputStream;
import java.io.FileNotFoundException;
import java.io.InputStream;
import java.util.Date;

public class Security {
    public Certificate getCertificate(File certFile) throws CertificateExpiredException, CertificateNotYetValidException {
        X509Certificate cert = null;
        try {
            InputStream inStream = new FileInputStream(certFile);
            cert = X509Certificate.getInstance(inStream);
        } catch (CertificateException e) {
            throw new RuntimeException(e);
        } catch (FileNotFoundException e) {
            throw new RuntimeException(e);
        }
        cert.checkValidity(new Date());
        return cert;
    }

}

Amazon Q changing dependency from javax.security to java.security package and fixing compilation errors related to X509Certificate . It modified the code to get the X509Certificate from CertificateFactory instead of directly getting from the X509Certificate.getInstance.

import java.security.cert.*;
import java.io.File;
import java.io.FileInputStream;
import java.io.FileNotFoundException;
import java.io.InputStream;
import java.util.Date;

public class Security {
    public Certificate getCertificate(File certFile) throws CertificateExpiredException, CertificateNotYetValidException {
        X509Certificate cert = null;
        try {
            InputStream inStream = new FileInputStream(certFile);
            CertificateFactory cf = CertificateFactory.getInstance("X.509");
            cert = (X509Certificate) cf.generateCertificate(inStream);
        } catch (CertificateException e) {
            throw new RuntimeException(e);
        } catch (FileNotFoundException e) {
            throw new RuntimeException(e);
        }
        cert.checkValidity(new Date());
        return cert;
    }

}

With Q Developer’s AI technology, it can automatically correct a wider range of issues that would otherwise require manual intervention, further streamlining the upgrade process and reducing the risk of costly delays or regressions.

AI Technology GIF

Conclusion

Throughout this blog post, we explored the three major areas of improvement in the Amazon Q Developer agent for code transformation since its general availability: major version upgrades of popular frameworks, direct replacement of deprecated library calls, and leveraging our AI technology using Amazon Bedrock capabilities to correct compilation errors during Java 17 migration. By addressing these critical aspects, the Q Developer agent has become an even more powerful tool for organizations seeking to unlock the benefits of Java 17 while minimizing the time and effort required for application upgrades. As we continue to enhance the Q Developer agent based on customer feedback, we encourage you to explore the open source example application provided and experience firsthand how this tool can streamline your Java modernization journey. See Getting Started with Amazon Q Developer agent for code transformation for a step by step process to transforming a java application with Q Developer.

About the authors

Jonathan-VogelJonathan Vogel

Jonathan is a Developer Advocate at AWS. He was a DevOps Specialist Solutions Architect at AWS for two years prior to taking on the Developer Advocate role. Prior to AWS, he practiced professional software development for over a decade. Jonathan enjoys music, birding and climbing rocks.


Venugopalan Vasudevan

Venugopalan is a Senior Specialist Solutions Architect at Amazon Web Services (AWS), where he specializes in AWS Generative AI services. His expertise lies in helping customers leverage cutting-edge services like Amazon Q, and Amazon Bedrock to streamline development processes, accelerate innovation, and drive digital transformation.