Tag Archives: serverless

Running code after returning a response from an AWS Lambda function

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/running-code-after-returning-a-response-from-an-aws-lambda-function/

This post is written by Uri Segev, Principal Serverless Specialist SA.

When you invoke an AWS Lambda function synchronously, you expect the function to return a response. For example, this is the case when a client invokes a Lambda function through Amazon API Gateway or from AWS Step Functions. As the client is waiting for the response, you should return the response as soon as possible.

However, there may be instances where you must perform additional work that does not affect the response and you can do it asynchronously, after you send the response. For example, you may store data in a database or send information to a logging system.

Once you send the response from the function, the Lambda service freezes the runtime environment, and the function cannot run additional code. Even if you create a thread for running a task in the background, the Lambda service freezes the runtime environment once the handler returns, causing the thread to freeze until the next invocation. While you can delay returning the response to the client until all work is complete, this approach can negatively impact the user experience.

This blog explores ways to run a task that may start before the function returns but continues running after the function returns the response to the client.

Invoking an asynchronous Lambda function

The first option is to break the code into two functions. The first function runs the synchronous code; the second function runs the asynchronous code. Before the synchronous function returns, it invokes the second function asynchronously, either directly, using the Invoke API, or indirectly, for example, by sending a message to Amazon SQS to trigger the second function.

This Python code demonstrates how to implement this:

import json
import time
import os
import boto3
from aws_lambda_powertools import Logger

logger = Logger()
client = boto3.client('lambda')

def calc_response(event):
    logger.info(f"[Function] Calculating response")
    time.sleep(1) # Simulate sync work
    return {
        "message": "hello from async"
    }

def submit_async_task(response):
    # Invoke async function to continue
    logger.info(f"[Function] Invoking async task in async function")
    client.invoke_async(FunctionName=os.getenv('ASYNC_FUNCTION'), InvokeArgs=json.dumps(response))

def handler(event, context):
    logger.info(f"[Function] Received event: {json.dumps(event)}")

    response = calc_response(event)
    
    # Done calculating response, submit async task
    submit_async_task(response)

    # Return response to client
    logger.info(f"[Function] Returning response to client")
    return {
        "statusCode": 200,
        "body": json.dumps(response)
    }

The following is the Lambda function that performs the asynchronous work:

import json
import time
from aws_lambda_powertools import Logger

logger = Logger()

def handler(event, context):
    logger.info(f"[Async task] Starting async task: {json.dumps(event)}")
    time.sleep(3)  # Simulate async work
    logger.info(f"[Async task] Done")

Use Lambda response streaming

Response streaming enables developers to start streaming the response as soon as they have the first byte of the response, without waiting for the entire response. You usually use response streaming when you must minimize the Time to First Byte (TTFB) or when you must send a response that is larger than 6 MB (the Lambda response payload size limit).

Using this method, the function can send the response using the response streaming mechanism and can continue running code even after sending the last byte of the response. This way, the client receives the response, and the Lambda function can continue running.

This Node.js code demonstrates how to implement this:

import { Logger } from '@aws-lambda-powertools/logger';

const logger = new Logger();

export const handler = awslambda.streamifyResponse(async (event, responseStream, _context) => {
    logger.info("[Function] Received event: ", event);
  
    // Do some stuff with event
    let response = await calc_response(event);
    
    // Return response to client
    logger.info("[Function] Returning response to client");
    responseStream.setContentType('application/json');
    responseStream.write(response);
    responseStream.end();

    await async_task(response);   
});

const calc_response = async (event) => {
    logger.info("[Function] Calculating response");
    await sleep(1);  // Simulate sync work

    return {
        message: "hello from streaming"
    };
};

const async_task = async (response) => {
    logger.info("[Async task] Starting async task");
    await sleep(3);  // Simulate async work
    logger.info("[Async task] Done");
};

const sleep = async (sec) => {
    return new Promise((resolve) => {
        setTimeout(resolve, sec * 1000);
    });
};

Use Lambda extensions

Lambda extensions can augment Lambda functions to integrate with your preferred monitoring, observability, security, and governance tools. You can also use an extension to run your own code in the background so that it continues running after your function returns the response to the client.

There are two types of Lambda extensions: external extensions and internal extensions. External extensions run as separate processes in the same execution environment. The Lambda function can communicate with the extension using files in the /tmp folder or using a local network, for example, via HTTP requests. You must package external extensions as a Lambda layer.

Internal extensions run as separate threads within the same process that runs the handler. The handler can communicate with the extension using any in-process mechanism, such as internal queues. This example shows an internal extension, which is a dedicated thread within the handler process.

When the Lambda service invokes a function, it also notifies all the extensions of the invocation. The Lambda service only freezes the execution environment when the Lambda function returns a response and all the extensions signal to the runtime that they are finished. With this approach, the function has the extension run the task independently from the function itself and the extension notifies the Lambda runtime when it is done processing the task. This way, the execution environment stays active until the task is done.

The following Python code example isolates the extension code into its own file and the handler imports and uses it to run the background task:

import json
import time
import async_processor as ap
from aws_lambda_powertools import Logger

logger = Logger()

def calc_response(event):
    logger.info(f"[Function] Calculating response")
    time.sleep(1) # Simulate sync work
    return {
        "message": "hello from extension"
    }

# This function is performed after the handler code calls submit_async_task 
# and it can continue running after the function returns
def async_task(response):
    logger.info(f"[Async task] Starting async task: {json.dumps(response)}")
    time.sleep(3)  # Simulate async work
    logger.info(f"[Async task] Done")

def handler(event, context):
    logger.info(f"[Function] Received event: {json.dumps(event)}")

    # Calculate response
    response = calc_response(event)

    # Done calculating response
    # call async processor to continue
    logger.info(f"[Function] Invoking async task in extension")
    ap.start_async_task(async_task, response)

    # Return response to client
    logger.info(f"[Function] Returning response to client")
    return {
        "statusCode": 200,
        "body": json.dumps(response)
    }

The following Python code demonstrates how to implement the extension that runs the background task:

import os
import requests
import threading
import queue
from aws_lambda_powertools import Logger

logger = Logger()
LAMBDA_EXTENSION_NAME = "AsyncProcessor"

# An internal queue used by the handler to notify the extension that it can
# start processing the async task.
async_tasks_queue = queue.Queue()

def start_async_processor():
    # Register internal extension
    logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Registering with Lambda service...")
    response = requests.post(
        url=f"http://{os.environ['AWS_LAMBDA_RUNTIME_API']}/2020-01-01/extension/register",
        json={'events': ['INVOKE']},
        headers={'Lambda-Extension-Name': LAMBDA_EXTENSION_NAME}
    )
    ext_id = response.headers['Lambda-Extension-Identifier']
    logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Registered with ID: {ext_id}")

    def process_tasks():
        while True:
            # Call /next to get notified when there is a new invocation and let
            # Lambda know that we are done processing the previous task.

            logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Waiting for invocation...")
            response = requests.get(
                url=f"http://{os.environ['AWS_LAMBDA_RUNTIME_API']}/2020-01-01/extension/event/next",
                headers={'Lambda-Extension-Identifier': ext_id},
                timeout=None
            )

            # Get next task from internal queue
            logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Wok up, waiting for async task from handler")
            async_task, args = async_tasks_queue.get()
            
            if async_task is None:
                # No task to run this invocation
                logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Received null task. Ignoring.")
            else:
                # Invoke task
                logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Received async task from handler. Starting task.")
                async_task(args)
            
            logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Finished processing task")

    # Start processing extension events in a separate thread
    threading.Thread(target=process_tasks, daemon=True, name='AsyncProcessor').start()

# Used by the function to indicate that there is work that needs to be 
# performed by the async task processor
def start_async_task(async_task=None, args=None):
    async_tasks_queue.put((async_task, args))

# Starts the async task processor
start_async_processor()

Use a custom runtime

Lambda supports several runtimes out of the box: Python, Node.js, Java, Dotnet, and Ruby. Lambda also supports custom runtimes, which lets you develop Lambda functions in any other programming language that you need to.

When you invoke a Lambda function that uses a custom runtime, the Lambda service invokes a process called ‘bootstrap’ that contains your custom code. The custom code needs to interact with the Lambda Runtime API. It calls the /next endpoint to obtain information about the next invocation. This API call is blocking and it waits until a request arrives. When the function is done processing the request, it must call the /response endpoint to send the response back to the client and then it must call the /next endpoint again to wait for the next invocation. Lambda freezes the execution environment after you call /next, until a request arrives.

Using this approach, you can run the asynchronous task after calling /response, and sending the response back to the client, and before calling /next, indicating that the processing is done.

The following Python code example isolates the custom runtime code into its own file and the function imports and uses it to interact with the runtime API:

import time
import json
import runtime_interface as rt
from aws_lambda_powertools import Logger

logger = Logger()

def calc_response(event):
    logger.info(f"[Function] Calculating response")
    time.sleep(1) # Simulate sync work
    return {
        "message": "hello from custom"
    }

def async_task(response):
    logger.info(f"[Async task] Starting async task: {json.dumps(response)}")
    time.sleep(3)  # Simulate async work
    logger.info(f"[Async task] Done")

def main():
    # You can add initialization code here

    # The following loop runs forever waiting for the next invocation
    # and sending the response back to the client
    while True:
        # Call /next to wait for next request (and indicate 
        # that we are done processing the previous request)

        requestId, event = rt.get_next()

        # The code from here to send_response() is the code
        # that usually goes inside the Lambda handler()

        logger.info(f"[Function] Received event: {json.dumps(event)}")

        # Calculate response
        response = calc_response(event)

        # Done calculating response, send response to client
        logger.info(f"[Function] Returning response to client")
        rt.send_response(requestId, {
            "statusCode": 200,
            "body": json.dumps(response)
        })

        logger.info(f"[Function] Invoking async task")
        async_task(response)

main()

This Python code demonstrates how to interact with the runtime API:

import requests
import os
from aws_lambda_powertools import Logger

logger = Logger()
run_time_endpoint = os.environ['AWS_LAMBDA_RUNTIME_API']

def get_next():
    logger.debug("[Custom runtime] Waiting for invocation...")
    request = requests.get(
        url=f"http://{run_time_endpoint}/2018-06-01/runtime/invocation/next",
        timeout=None
    )
    event = request.json()
    requestId = request.headers["Lambda-Runtime-Aws-Request-Id"]
    return requestId, event

def send_response(requestId, response):
    logger.debug("[Custom runtime] Sending response")
    requests.post(
        url=f"http://{run_time_endpoint}/2018-06-01/runtime/invocation/{requestId}/response",
        json = response,
        timeout=None
    )

Conclusion

This blog shows four ways of combining synchronous and asynchronous tasks in a Lambda function, allowing you to run tasks that continue running after the function returns a response to the client. The following table summarizes the pros and cons of each solution:

Function URLs, cannot be used with API Gateway, always public

Asynchronous invocation Response streaming Lambda extensions Custom runtime
Complexity Easier to implement Easiest to implement The most complex solution to implement as it requires interacting with the extensions API and a dedicated thread Medium as it interacts with the runtime API
Deployment Need two artifacts: the synchronous function and the asynchronous function A single deployment artifact that contains all code A single deployment artifact that contains all code A single deployment artifact, requires packaging all needed runtime files
Cost Most expensive as it incurs additional invocation cost as well as the overall duration of both functions is higher than having it in one Least expensive Least expensive Least expensive
Starting the async task Before returning from handler Anytime during the handler invocation Anytime during the handler invocation After returning the response to the client, unless you use a dedicated thread
Limitations Payload sent to the asynchronous function cannot exceed 256 KB Only supported with Node.js and custom runtimes. Requires Lambda Function URLs, cannot be used with API Gateway, always public – –
Additional benefits Better decoupling between synchronous and asynchronous code Ability to send response in stages. Supports payloads larger than 6 MB (at additional cost) The asynchronous task runs in its own thread, which can reduce overall duration and cost –
Retries in case of failure in async code Managed by the Lambda service Responsibility of the developer Responsibility of the developer Responsibility of the developer

Choosing the right approach depends on your use case. If you write your function in Node.js and you invoke it using Lambda Function URLs, use response streaming. This is the easiest way to implement, and it is the most cost effective.

If there is a chance for a failure in the asynchronous task (for example, a database is not accessible), and you must ensure that the task completes, use the asynchronous Lambda invocation method. The Lambda service retries your asynchronous function until it succeeds. Eventually, if all retries fail, it invokes a Lambda destination so you can take action.

If you need a custom runtime because you need to use a programming language that Lambda does not natively support, use the custom runtime option. Otherwise, use the Lambda extensions option. It is more complex to implement, but it is cost effective. This allows you to package the code in a single artifact and start processing the asynchronous task before you send the response to the client.

For more serverless learning resources, visit Serverless Land.

Accelerating workflow development with the TestState API in AWS Step Functions

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/accelerating-workflow-development-with-the-teststate-api-in-aws-step-functions/

This post is written by Ben Freiberg, Senior Solutions Architect.

Developers often choose AWS Step Functions to orchestrate the services that comprise their applications. Step Functions is a visual workflow service that makes it easier for developers to build distributed applications, automate processes, orchestrate microservices, and create data and machine learning (ML) pipelines. Step Functions integrates with over 220 AWS services and any publicly accessible HTTP endpoint. Step Functions provides many features that help developers build, such as built-in error handling, real-time and auditable workflow execution history, and large-scale parallel processing.

Several areas can be time consuming for developers when testing Step Functions workflows. For example, authentication with external services, input/output processing, AWS IAM permission, or intrinsic functions. To simplify and speed up resolving these issues, Step Functions released a new capability last year to test individual states: the TestState API. This feature allows you to test states independently from the execution of your workflow. You can change the input and test different scenarios without the need to deploy your workflow or execute the whole state machine. This feature is available for all task, choice, and pass states.

Since developers spend significant time in IDEs and terminals, TestState is also available via an API. This allows you to iterate over changes for an individual state and lets you refine the input/output processing or conditional logic in a choice state without leaving your IDE. In this post, you’ll learn how the TestState API can speed up your testing and development.

Getting started with TestState

Suppose that you are developing a payment processing workflow that consists of three states. First, a Choice state that checks the type of payment based on the input data. Depending on the type, it calls either an AWS Lambda function or an external endpoint. The task state that invokes the Lambda function includes some input/output processing.

Getting started with TestState

To get started with the TestState API, you must create an IAM role that the service can assume. The role must contain the required IAM permissions for the resources your state is accessing. For information about the permissions a state might need, see IAM permissions to test a state. The following snippet shows the minimal necessary permissions:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "states:TestState",
        "iam:PassRole"
      ],
      "Resource": "*"
    }
  ]
}

Next, you must provide the definition of the state being tested. The choice state is configured to check the type of payment and if the voucherId is present, in case of a voucher. The following snippet shows the state definition:

{
    "Type": "Choice",
    "Choices": [
        {
            "And": [
                {
                    "Variable": "$.payment.type",
                    "IsPresent": true
                },
                {
                    "Variable": "$.payment.type",
                    "StringEquals": "voucher"
                }
            ],
            "Next": "Process voucher"
        },
        {
            "Variable": "$.payment.type",
            "StringEquals": "credit",
            "Next": "Call payment provider"
        }
    ],
    "Default": "Fail"
}

Using the role and state definition, you can now test it if an input results in the expected next state:

aws stepfunctions test-state 
--definition file://choice.json 
--role-arn "arn:aws:iam::<account-id>:role/StepFunctions-TestState-Role" 
--input '{"payment":{"type":"voucher"}}'

The response shows that the test did not encounter any errors and that the next state would be invoking the Lambda function to process the voucher as expected.

{
    "output": "{\"payment\":{\"type\":\"voucher\"}}",
    "nextState": "Process voucher",
    "status": "SUCCEEDED"
}

Similarly, with a payment type of credit as input, the next state is invoking the third-party endpoint:

aws stepfunctions test-state
--definition file://choice.json
--role-arn "arn:aws:iam::<account-id>:role/StepFunctions-TestState-Role"
--input '{"payment":{"type":"credit"}}'
{
    "output": "{\"payment\":{\"type\":\"credit\"}}",
    "nextState": "Call payment provider",
    "status": "SUCCEEDED"
}

Because the TestState API takes the state definition as an argument, you do not have to redeploy the state machine when changing the state definition. Instead, you can iterate and test your settings by passing the modified state definition to the TestState API.

Using inspection levels

For each state, you can specify the amount of detail you want to view in the test results. These details provide additional information about the state that you are testing. For example, if you’ve used any input and output data processing filters, such as InputPath or ResultPath in a state, you can view the intermediate and final data processing results. Step Functions provides the following levels to specify the details you want to view, INFO, DEBUG, and TRACE. All these levels return the status and nextState fields.

Next, the Lambda Invoke state is tested. In this scenario, the state includes input/output processing. The output from the function is transformed by renaming and restructuring the field and then merged with the original input. This is the relevant part of the task definition:

"Process voucher": {
      "Type": "Task",
      "Resource": "arn:aws:states:::lambda:invoke",
      "Parameters": {...},
      "Retry": [...],
      "Next": "Success",
      "ResultPath": "$.voucherProcessed",
      "ResultSelector": {
        "status.$": "$.Payload.result",
        "workflowId.$": "$.Payload.workflow"
      }
}

This time test using the Step Functions console, which can make it easier to understand the input/output processing steps. To get started, open the state machine in Workflow Studio and select the state, and then choose Test State. Make sure to select DEBUG as the inspection level. After testing the state, switch to the Input/output processing tab to check the intermediate steps.

Input/output processing tab

When you call the TestState API and set the inspectionLevel parameter to DEBUG, the API response includes an object called inspectionData. This object contains fields to help you inspect how data was filtered or manipulated within the state when it was executed. This data is shown in the Input/output processing tab in the console.

Being able to see all the processing steps easily in one place allows developers to spot issues and iterate more quickly, saving time.

Testing third-party endpoint integrations

Applications might call third-party endpoints that require authentication. Step Functions offers the HTTPS endpoint resource to connect to third-party HTTP targets outside of the AWS Cloud.

HTTPS endpoints use Amazon EventBridge connections to manage the authentication credentials for the target. This defines the authorization type used, which can be a basic authentication with a username and password, an API key, or OAuth. EventBridge connections use AWS Secrets Manager to store the secret. This keeps the secrets out of the state machine, reducing the risks of accidentally exposing your secrets in logs or in the state machine definition.

Getting the authentication configuration right might involve several time-consuming iterations. With the TRACE inspection level, developers can see the raw HTTP request and response, which is useful for verifying headers, query parameters, and other API-specific details. This option is only available for the HTTP Task. You can also view the secrets included in the EventBridge connection. To do this, you must set the revealSecrets parameter to true in the TestState API. This can help verifying that the correct authentication parameters are used.

To get started, ensure that the execution role used for testing has the necessary permissions, as shown here:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "secretsmanager:GetSecretValue",
                "secretsmanager:DescribeSecret"
            ],
            "Resource": "arn:aws:secretsmanager:<your-region>:<account-id>:secret:events!connection/<your-connection-id>"
        }
    ]
}
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "RetrieveConnectionCredentials",
            "Effect": "Allow",
            "Action": [
                "events:RetrieveConnectionCredentials"
            ],
            "Resource": [
                "arn:aws:events:<your-region>:<account-id>:connection/<your-connection-id>"
            ]
        }
    ]
}
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "InvokeHTTPEndpoint",
            "Effect": "Allow",
            "Action": [
                "states:InvokeHTTPEndpoint"
            ],
            "Resource": [
                "arn:aws:states:<your-region>:<account-id>:stateMachine:<your-statemachine>"
            ]
        }
    ]
}

When you test the HTTP task, make sure to set the inspection level to TRACE. Then use the HTTP request and response tab to check the details. This capability saves you time when debugging complex authentication issues.

set the inspection level to TRACE

Automating testing

Testing is not only a manual activity to get the configuration right. Most often, tests are run as part of a suite of tests, which are automatically performed to validate the correct behavior. It also prevents regressions when making changes. The TestState API can easily be integrated in such tests as well.

The following snippet shows a test using the Jest framework in JavaScript. The test checks if the correct next state is produced given a definition and input. The definition resides in a different file, which can also be used for infrastructure as code (IaC) to create the state machine.

const { SFNClient, TestStateCommand } = require("@aws-sdk/client-sfn");
// Import the state definition 
const definition = require("./definition.json");

const client = new SFNClient({});

describe("Step Functions", () => {
  test("that next state is correct", async () => {
    const command = new TestStateCommand({
      definition: JSON.stringify(definition),
      roleArn: "arn:aws:iam::<account-id>:role/<role-with-sufficient-permissions>",
      input: "{}" # Adjust as necessary
    });
    const data = await client.send(command);

    expect(data.status).toBe("SUCCEEDED");
    expect(data.nextState).toBe("Success"); # Adjust as necessary
  });
});

With automated tests, you can safely change your workflow definitions without the need for manual efforts. That way, you are immediately alerted if a change would result in an incompatibility.

With TestState you can increase your test coverage with less effort because you can test states directly. This is especially helpful for complex workflows and states that require a specific set of circumstances to reach them. It makes it easier to validate the correctness of your error-handling as well. You can now test the potentially many combinations of your configured Retriers and Catchers much easier.

Conclusion

The TestState API helps developers to iterate faster, resolve issues efficiently, and deliver high-quality applications with greater confidence. By enabling developers to test individual states independently and integrating testing into their preferred development workflows, it simplifies the debugging process and reduces context switches. Whether testing input/output processing, authentication with external services, or third-party endpoint integrations, the TestState API can be a useful tool for testing.

Analyze more demanding as well as larger time series workloads with Amazon OpenSearch Serverless 

Post Syndicated from Satish Nandi original https://aws.amazon.com/blogs/big-data/analyze-more-demanding-as-well-as-larger-time-series-workloads-with-amazon-opensearch-serverless/

In today’s data-driven landscape, managing and analyzing vast amounts of data, especially logs, is crucial for organizations to derive insights and make informed decisions. However, handling this data efficiently presents a significant challenge, prompting organizations to seek scalable solutions without the complexity of infrastructure management.

Amazon OpenSearch Serverless lets you run OpenSearch in the AWS Cloud, without worrying about scaling infrastructure. With OpenSearch Serverless, you can ingest, analyze, and visualize your time-series data. Without the need for infrastructure provisioning, OpenSearch Serverless simplifies data management and enables you to derive actionable insights from extensive repositories.

We recently announced a new capacity level of 10TB for Time-series data per account per Region, which includes one or more indexes within a collection. With the support for larger datasets, you can unlock valuable operational insights and make data-driven decisions to troubleshoot application downtime, improve system performance, or identify fraudulent activities.

In this post, we discuss this new capability and how you can analyze larger time series datasets with OpenSearch Serverless.

10TB Time-series data size support in OpenSearch Serverless

The compute capacity for data ingestion and search or query in OpenSearch Serverless is measured in OpenSearch Compute Units (OCUs). These OCUs are shared among various collections, each containing one or more indexes within the account. To accommodate larger datasets, OpenSearch Serverless now supports up to 200 OCUs per account per AWS Region, each for indexing and search respectively, doubling from the previous limit of 100. You configure the maximum OCU limits on search and indexing independently to manage costs. You can also monitor real-time OCU usage with Amazon CloudWatch metrics to gain a better perspective on your workload’s resource consumption.

Dealing with larger data and analysis needs more memory and CPU. With 10TB data size support, OpenSearch Serverless is introducing vertical scaling up to eight times of 1-OCU systems. For example, the OpenSearch Serverless will deploy a larger system equivalent of eight 1-OCU systems. The system will use hybrid of horizontal and vertical scaling to address the needs of the workloads. There are improvements to shard reallocation algorithm to reduce the shard movement during heat remediation, vertical scaling, or routine deployment.

In our internal testing for 10TB Time-series data, we set the Max OCU to 48 for Search and 48 for Indexing. We set the data retention for 5 days using data lifecycle policies, and set the deployment type to “Enable redundancy” making sure the data is replicated across Availability Zones . This will lead to 12_24 hours of data in hot storage (OCU disk memory) and the rest in Amazon Simple Service (Amazon S3) storage. We observed the average ingestion achieved was 2.3 TiB per day with an average ingestion performance of 49.15 GiB per OCU per day, reaching a max of 52.47 GiB per OCU per day and a minimum of 32.69 Gib per OCU per day in our testing. The performance depends on several aspects, like document size, mapping, and other parameters, which may or may not have a variation for your workload.

Set max OCU to 200

You can start using our expanded capacity today by setting your OCU limits for indexing and search to 200. You can still set the limits to less than 200 to maintain a maximum cost during high traffic spikes. You only pay for the resources consumed, not for the max OCU configuration.

Ingest the data

You can use the load generation scripts shared in the following workshop, or you can use your own application or data generator to create a load. You can run multiple instances of these scripts to generate a burst in indexing requests. As shown in the following screenshot, we tested with an index, sending approximately 10 TB of data. We used our load generator script to send the traffic to a single index, retaining data for 5 days, and used a data life cycle policy to delete data older than 5 days.

Auto scaling in OpenSearch Serverless with new vertical scaling.

Before this release, OpenSearch Serverless auto-scaled by horizontally adding the same-size capacity to handle increases in traffic or load. With the new feature of vertical scaling to a larger size capacity, it can optimize the workload by providing a more powerful compute unit. The system will intelligently decide whether horizontal scaling or vertical scaling is more price-performance optimal. Vertical scaling also improves auto-scaling responsiveness, because vertical scaling helps to reach the optimal capacity faster compared to the incremental steps taken through horizontal scaling. Overall, vertical scaling has significantly improved the response time for auto_scaling.

Conclusion

We encourage you to take advantage of the 10TB index support and put it to the test! Migrate your data, explore the improved throughput, and take advantage of the enhanced scaling capabilities. Our goal is to deliver a seamless and efficient experience that aligns with your requirements.

To get started, refer to Log analytics the easy way with Amazon OpenSearch Serverless. To get hands-on experience with OpenSearch Serverless, follow the Getting started with Amazon OpenSearch Serverless workshop, which has a step-by-step guide for configuring and setting up an OpenSearch Serverless collection.

If you have feedback about this post, share it in the comments section. If you have questions about this post, start a new thread on the Amazon OpenSearch Service forum or contact AWS Support.


About the authors

Satish Nandi is a Senior Product Manager with Amazon OpenSearch Service. He is focused on OpenSearch Serverless and has years of experience in networking, security and ML/AI. He holds a Bachelor’s degree in Computer Science and an MBA in Entrepreneurship. In his free time, he likes to fly airplanes, hang gliders and ride his motorcycle.

Michelle Xue is Sr. Software Development Manager working on Amazon OpenSearch Serverless. She works closely with customers to help them onboard OpenSearch Serverless and incorporates customer’s feedback into their Serverless roadmap. Outside of work, she enjoys hiking and playing tennis.

Prashant Agrawal is a Sr. Search Specialist Solutions Architect with Amazon OpenSearch Service. He works closely with customers to help them migrate their workloads to the cloud and helps existing customers fine-tune their clusters to achieve better performance and save on cost. Before joining AWS, he helped various customers use OpenSearch and Elasticsearch for their search and log analytics use cases. When not working, you can find him traveling and exploring new places. In short, he likes doing Eat → Travel → Repeat.

Using Amazon Verified Permissions to manage authorization for AWS IoT smart home applications

Post Syndicated from Rajat Mathur original https://aws.amazon.com/blogs/security/using-amazon-verified-permissions-to-manage-authorization-for-aws-iot-smart-thermostat-applications/

This blog post introduces how manufacturers and smart appliance consumers can use Amazon Verified Permissions to centrally manage permissions and fine-grained authorizations. Developers can offer more intuitive, user-friendly experiences by designing interfaces that align with user personas and multi-tenancy authorization strategies, which can lead to higher user satisfaction and adoption. Traditionally, implementing authorization logic using role based access control (RBAC) or attribute based access control (ABAC) within IoT applications can become complex as the number of connected devices and associated user roles grows. This often leads to an unmanageable increase in access rules that must be hard-coded into each application, requiring excessive compute power for evaluation. By using Verified Permissions, you can externalize the authorization logic using Cedar policy language, enabling you to define fine-grained permissions that combine RBAC and ABAC models. This decouples permissions from your application’s business logic, providing a centralized and scalable way to manage authorization while reducing development effort.

In this post, we walk you through a reference architecture that outlines an end-to-end smart thermostat application solution using AWS IoT Core, Verified Permissions, and other AWS services. We show you how to use Verified Permissions to build an authorization solution using Cedar policy language to define dynamic policy-based access controls for different user personas. The post includes a link to a GitHub repository that houses the code for the web dashboard and the Verified Permissions logic to control access to the solution APIs.

Solution overview

This solution consists of a smart thermostat IoT device and an AWS hosted web application using Verified Permissions for fine-grained access to various application APIs. For this use case, the AWS IoT Core device is being simulated by an AWS Cloud9 environment and communicates with the IoT service using AWS IoT Device SDK for Python. After being configured, the device connects to AWS IoT Core to receive commands and send messages to various MQTT topics.

As a general practice, when a user-facing IoT solution is implemented, the manufacturer performs administrative tasks such as:

  1. Embedding AWS Private Certificate Authority certificates into each IoT device (in this case a smart thermostat). Usually this is done on the assembly line and the certificates used to verify the IoT endpoints are burned into device memory along with the firmware.
  2. Creating an Amazon Cognito user pool that provides sign-up and sign-in options for web and mobile application users and hosts the authentication process.
  3. Creating policy stores and policy templates in Verified Permissions. Based on who signs up, the manufacturer creates policies with Verified Permissions to link each signed-up user to certain allowed resources or IoT devices.
  4. The mapping of user to device is stored in a datastore. For this solution, you’ll use an Amazon DynamoDB table to record the relationship.

The user who purchases the device (the primary device owner) performs the following tasks:

  1. Signs up on the manufacturer’s web application or mobile app and registers the IoT device by entering a unique serial number. The mapping between user details and the device serial number is stored in the datastore through an automated process that is initiated after sign-up and device claim.
  2. Connects the new device to an existing wireless network, which initiates a registration process to securely connect to AWS IoT Core services within the manufacturer’s account.
  3. Invites other users (such as guests, family members, or the power company) through a referral, invitation link, or a designated OAuth process.
  4. Assign roles to the other users and therefore permissions.
     
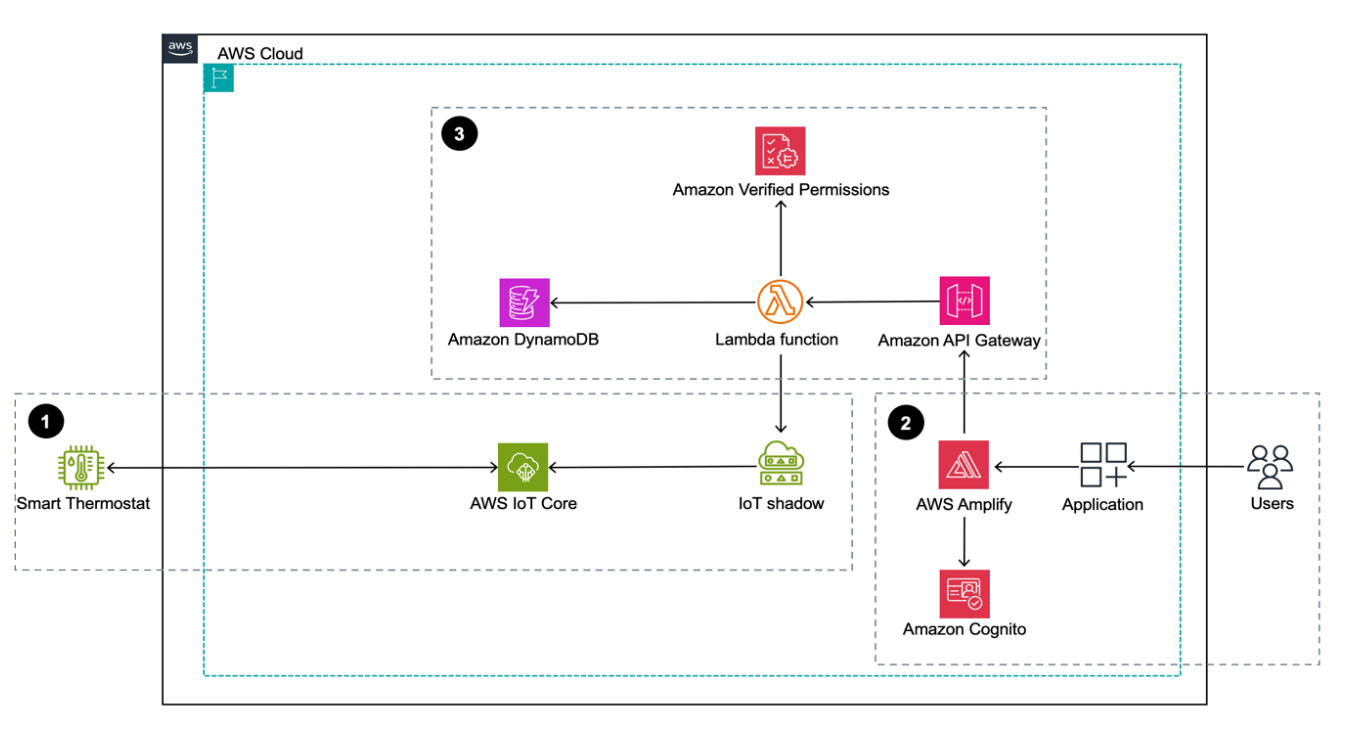
Figure 1: Sample smart home application architecture built using AWS services

Figure 1: Sample smart home application architecture built using AWS services

Figure 1 depicts the solution as three logical components:

  1. The first component depicts device operations through AWS IoT Core. The smart thermostat is on site and it communicates with AWS IoT Core and its state is managed through the AWS IoT Device Shadow Service.
  2. The second component depicts the web application, which is the application interface that customers use. It’s a ReactJS-backed single page application deployed using AWS Amplify.
  3. The third component shows the backend application, which is built using Amazon API Gateway, AWS Lambda, and DynamoDB. A Cognito user pool is used to manage application users and their authentication. Authorization is handled by Verified Permissions where you create and manage policies that are evaluated when the web application calls backend APIs. These policies are evaluated against each authorization policy to provide an access decision to deny or allow an action.

The solution flow itself can be broken down into three steps after the device is onboarded and users have signed up:

  1. The smart thermostat device connects and communicates with AWS IoT Core using the MQTT protocol. A classic Device Shadow is created for the AWS IoT thing Thermostat1 when the UpdateThingShadow call is made the first time through the AWS SDK for a new device. AWS IoT Device Shadow service lets the web application query and update the device’s state in case of connectivity issues.
  2. Users sign up or sign in to the Amplify hosted smart home application and authenticate themselves against a Cognito user pool. They’re mapped to a device, which is stored in a DynamoDB table.
  3. After the users sign in, they’re allowed to perform certain tasks and view certain sections of the dashboard based on the different roles and policies managed by Verified Permissions. The underlying Lambda function that’s responsible for handling the API calls queries the DynamoDB table to provide user context to Verified Permissions.

Prerequisites

  1. To deploy this solution, you need access to the AWS Management Console and AWS Command Line Interface (AWS CLI) on your local machine with sufficient permissions to access required services, including Amplify, Verified Permissions, and AWS IoT Core. For this solution, you’ll give the services full access to interact with different underlying services. But in production, we recommend following security best practices with AWS Identity and Access Management (IAM), which involves scoping down policies.
  2. Set up Amplify CLI by following these instructions. We recommend the latest NodeJS stable long-term support (LTS) version. At the time of publishing this post, the LTS version was v20.11.1. Users can manage multiple NodeJS versions on their machines by using a tool such as Node Version Manager (nvm).

Walkthrough

The following table describes the actions, resources, and authorization decisions that will be enforced through Verified Permissions policies to achieve fine-grained access control. In this example, John is the primary device owner and has purchased and provisioned a new smart thermostat device called Thermostat1. He has invited Jane to access his device and has given her restricted permissions. John has full control over the device whereas Jane is only allowed to read the temperature and set the temperature between 72°F and 78°F.

John has also decided to give his local energy provider (Power Company) access to the device so that they can set the optimum temperature during the day to manage grid load and offer him maximum savings on his energy bill. However, they can only do so between 2:00 PM and 5:00 PM.

For security purposes the verified permissions default decision is DENY for unauthorized principals.

Name Principal Action Resource Authorization decision
Any Default Default Default Deny
John john_doe Any Thermostat1 Allow
Jane jane_doe GetTemperature Thermostat1 Allow
Jane jane_doe SetTemperature Thermostat1 Allow only if desired temperature is between 72°F and 78°F.
Power Company powercompany GetTemperature Thermostat1 Allow only if accessed between the hours of 2:00 PM and 5:00 PM
Power Company powercompany SetTemperature Thermostat1 Allow only if the temperature is set between the hours of 2:00 PM and 5:00 PM

Create a Verified Permissions policy store

Verified Permissions is a scalable permissions management and fine-grained authorization service for the applications that you build. The policies are created using Cedar, a dedicated language for defining access permissions in applications. Cedar seamlessly integrates with popular authorization models such as RBAC and ABAC.

A policy is a statement that either permits or forbids a principal to take one or more actions on a resource. A policy store is a logical container that stores your Cedar policies, schema, and principal sources. A schema helps you to validate your policy and identify errors based on the definitions you specify. See Cedar schema to learn about the structure and formal grammar of a Cedar schema.

To create the policy store

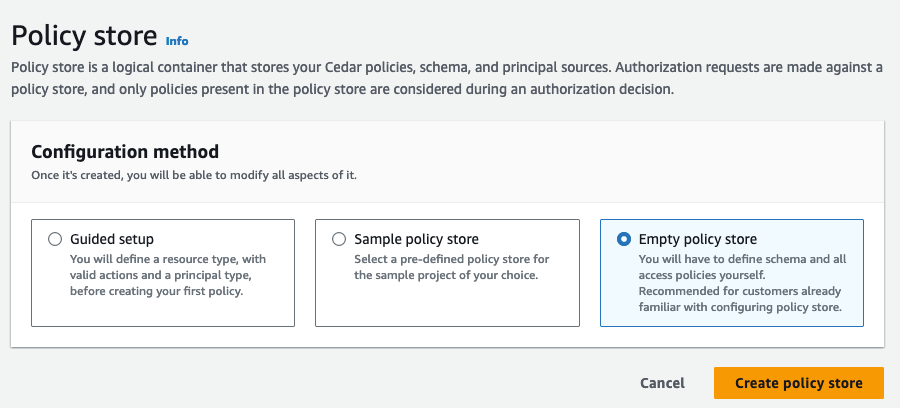
  1. Sign in to the Amazon Verified Permissions console and choose Create policy store.
  2. In the Configuration Method section, select Empty Policy Store and choose Create policy store.
     
Figure 2: Create an empty policy store

Figure 2: Create an empty policy store

Note: Make a note of the policy store ID to use when you deploy the solution.

To create a schema for the application

  1. On the Verified Permissions page, select Schema.
  2. In the Schema section, choose Create schema.
     
    Figure 3: Create a schema

    Figure 3: Create a schema

  3. In the Edit schema section, choose JSON mode, paste the following sample schema for your application, and choose Save changes.
    {
        "AwsIotAvpWebApp": {
            "entityTypes": {
                "Device": {
                    "shape": {
                        "attributes": {
                            "primaryOwner": {
                                "name": "User",
                                "required": true,
                                "type": "Entity"
                            }
                        },
                        "type": "Record"
                    },
                    "memberOfTypes": []
                },
                "User": {}
            },
            "actions": {
                "GetTemperature": {
                    "appliesTo": {
                        "context": {
                            "attributes": {
                                "desiredTemperature": {
                                    "type": "Long"
                                },
                                "time": {
                                    "type": "Long"
                                }
                            },
                            "type": "Record"
                        },
                        "resourceTypes": [
                            "Device"
                        ],
                        "principalTypes": [
                            "User"
                        ]
                    }
                },
                "SetTemperature": {
                    "appliesTo": {
                        "resourceTypes": [
                            "Device"
                        ],
                        "principalTypes": [
                            "User"
                        ],
                        "context": {
                            "attributes": {
                                "desiredTemperature": {
                                    "type": "Long"
                                },
                                "time": {
                                    "type": "Long"
                                }
                            },
                            "type": "Record"
                        }
                    }
                }
            }
        }
    }

When creating policies in Cedar, you can define authorization rules using a static policy or a template-linked policy.

Static policies

In scenarios where a policy explicitly defines both the principal and the resource, the policy is categorized as a static policy. These policies are immediately applicable for authorization decisions, as they are fully defined and ready for implementation.

Template-linked policies

On the other hand, there are situations where a single set of authorization rules needs to be applied across a variety of principals and resources. Consider an IoT application where actions such as SetTemperature and GetTemperature must be permitted for specific devices. Using static policies for each unique combination of principal and resource can lead to an excessive number of almost identical policies, differing only in their principal and resource components. This redundancy can be efficiently addressed with policy templates. Policy templates allow for the creation of policies using placeholders for the principal, the resource, or both. After a policy template is established, individual policies can be generated by referencing this template and specifying the desired principal and resource. These template-linked policies function the same as static policies, offering a streamlined and scalable solution for policy management.

To create a policy that allows access to the primary owner of the device using a static policy

  1. In the Verified Permissions console, on the left pane, select Policies, then choose Create policy and select Create static policy from the drop-down menu.
     
    Figure 4: Create static policy

    Figure 4: Create static policy

  2. Define the policy scope:
    1. Select Permit for the Policy effect.
       
      Figure 5: Define policy effect

      Figure 5: Define policy effect

    2. Select All Principals for Principals scope.
    3. Select All Resources for Resource scope.
    4. Select All Actions for Actions scope and choose Next.
       
      Figure 6: Define policy scope

      Figure 6: Define policy scope

  3. On the Details page, under Policy, paste the following full-access policy, which grants the primary owner permission to perform both SetTemperature and GetTemperature actions on the smart thermostat unconditionally. Choose Create policy.
    	permit (principal, action, resource)
    	when { resource.primaryOwner == principal };
    Figure 7: Write and review policy statement

    Figure 7: Write and review policy statement

To create a static policy to allow a guest user to read the temperature

In this example, the guest user is Jane (username: jane_doe).

  1. Create another static policy and specify the policy scope.
    1. Select Permit for the Policy effect.
       
      Figure 8: Define the policy effect

      Figure 8: Define the policy effect

    2. Select Specific principal for the Principals scope.
    3. Select AwsIotAvpWebApp::User and enter jane_doe.
       
      Figure 9: Define the policy scope

      Figure 9: Define the policy scope

    4. Select Specific resource for the Resources scope.
    5. Select AwsIotAvpWebApp::Device and enter Thermostat1.
    6. Select Specific set of actions for the Actions scope.
    7. Select GetTemperature and choose Next.
       
      Figure 10: Define resource and action scopes

      Figure 10: Define resource and action scopes

    8. Enter the Policy description: Allow jane_doe to read thermostat1.
    9. Choose Create policy.

Next, you will create reusable policy templates to manage policies efficiently. To create a policy template for a guest user with restricted temperature settings that limit the temperature range they can set to between 72°F and 78°F. In this case, the guest user is going to be Jane (username: jane_doe)

To create a reusable policy template

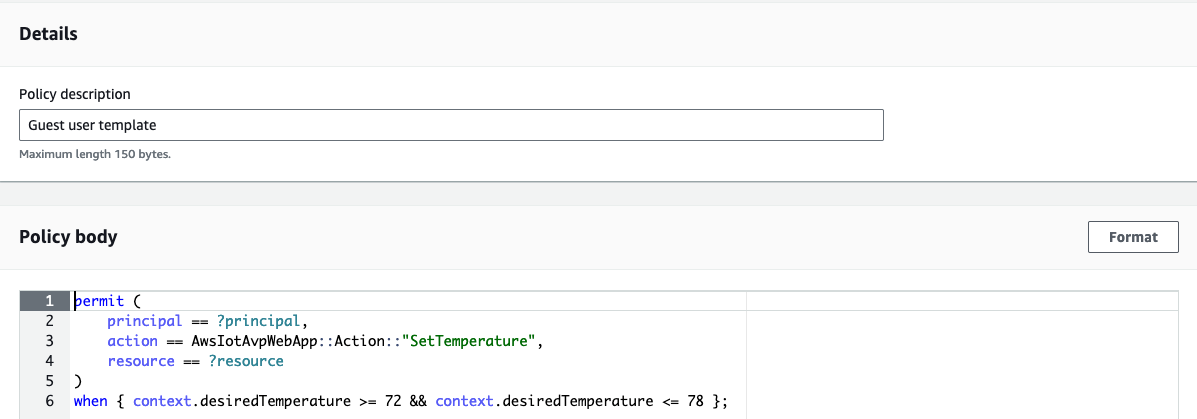
  1. Select Policy template and enter Guest user template as the description.
  2. Paste the following sample policy in the Policy body and choose Create policy template.
    permit (
        principal == ?principal,
        action in [AwsIotAvpWebApp::Action::"SetTemperature"],
        resource == ?resource
    )
    when { context.desiredTemperature >= 72 && context.desiredTemperature <= 78 };
Figure 11: Create guest user policy template

Figure 11: Create guest user policy template

As you can see, you don’t specify the principal and resource yet. You enter those when you create an actual policy from the policy template. The context object will be populated with the desiredTemperature property in the application and used to evaluate the decision.

You also need to create a policy template for the Power Company user with restricted time settings. Cedar policies don’t support date/time format, so you must represent 2:00 PM and 5:00 PM as elapsed minutes from midnight.

To create a policy template for the power company

  1. Select Policy template and enter Power company user template as the description.
  2. Paste the following sample policy in the Policy body and choose Create policy template.
    permit (
        principal == ?principal,
        action in [AwsIotAvpWebApp::Action::"SetTemperature", AwsIotAvpWebApp::Action::"GetTemperature"],
        resource == ?resource
    )
    when { context.time >= 840 && context.time < 1020 };

The policy templates accept the user and resource. The next step is to create a template-linked policy for Jane to set and get thermostat readings based on the Guest user template that you created earlier. For simplicity, you will manually create this policy using the Verified Permissions console. In production, application policies can be dynamically created using the Verified Permissions API.

To create a template-linked policy for a guest user

  1. In the Verified Permissions console, on the left pane, select Policies, then choose Create policy and select Create template-linked policy from the drop-down menu.
     
    Figure 12: Create new template-linked policy

    Figure 12: Create new template-linked policy

  2. Select the Guest user template and choose next.
     
    Figure 13: Select Guest user template

    Figure 13: Select Guest user template

  3. Under parameter selection:
    1. For Principal enter AwsIotAvpWebApp::User::”jane_doe”.
    2. For Resource enter AwsIotAvpWebApp::Device::”Thermostat1″.
    3. Choose Create template-linked policy.
       
      Figure 14: Create guest user template-linked policy

      Figure 14: Create guest user template-linked policy

Note that with this policy in place, jane_doe can only set the temperature of the device Thermostat1 to between 72°F and 78°F.

To create a template-linked policy for the power company user

Based on the template that was set up for power company, you now need an actual policy for it.

  1. In the Verified Permissions console, go to the left pane and select Policies, then choose Create policy and select Create template-linked policy from the drop-down menu.
  2. Select the Power company user template and choose next.
  3. Under Parameter selection, for Principal enter AwsIotAvpWebApp::User::”powercompany”, and for Resource enter AwsIotAvpWebApp::Device::”Thermostat1″, and choose Create template-linked policy.

Now that you have a set of policies in a policy store, you need to update the backend codebase to include this information and then deploy the web application using Amplify.

The policy statements in this post intentionally use human-readable values such as jane_doe and powercompany for the principal entity. This is useful when discussing general concepts but in production systems, customers should use unique and immutable values for entities. See Get the best out of Amazon Verified Permissions by using fine-grained authorization methods for more information.

Deploy the solution code from GitHub

Go to the GitHub repository to set up the Amplify web application. The repository Readme file provides detailed instructions on how to set up the web application. You will need your Verified Permissions policy store ID to deploy the application. For convenience, we’ve provided an onboarding script—deploy.sh—which you can use to deploy the application.

To deploy the application

  1. Close the repository.
    git clone https://github.com/aws-samples/amazon-verified-permissions-iot-
    amplify-smart-home-application.git

  2. Deploy the application.
    ./deploy.sh <region> <Verified Permissions Policy Store ID>

After the web dashboard has been deployed, you’ll create an IoT device using AWS IoT Core.

Create an IoT device and connect it to AWS IoT Core

With the users, policies, and templates, and the Amplify smart home application in place, you can now create a device and connect it to AWS IoT Core to complete the solution.

To create Thermostat1” device and connect it to AWS IoT Core

  1. From the left pane in the AWS IoT console, select Connect one device.
     
    Figure 15: Connect device using AWS IoT console

    Figure 15: Connect device using AWS IoT console

  2. Review how IoT Thing works and then choose Next.
     
    Figure 16: Review how IoT Thing works before proceeding

    Figure 16: Review how IoT Thing works before proceeding

  3. Choose Create a new thing and enter Thermostat1 as the Thing name and choose next.
    &bsp;
    Figure 17: Create the new IoT thing

    Figure 17: Create the new IoT thing

  4. Select Linux/macOS as the Device platform operating system and Python as the AWS IoT Core Device SDK and choose next.
     
    Figure 18: Choose the platform and SDK for the device

    Figure 18: Choose the platform and SDK for the device

  5. Choose Download connection kit and choose next.
     
    Figure 19: Download the connection kit to use for creating the Thermostat1 device

    Figure 19: Download the connection kit to use for creating the Thermostat1 device

  6. Review the three steps to display messages from your IoT device. You will use them to verify the thermostat1 IoT device connectivity to the AWS IoT Core platform. They are:
    1. Step 1: Add execution permissions
    2. Step 2: Run the start script
    3. Step 3: Return to the AWS IoT Console to view the device’s message
       
      Figure 20: How to display messages from an IoT device

      Figure 20: How to display messages from an IoT device

Solution validation

With all of the pieces in place, you can now test the solution.

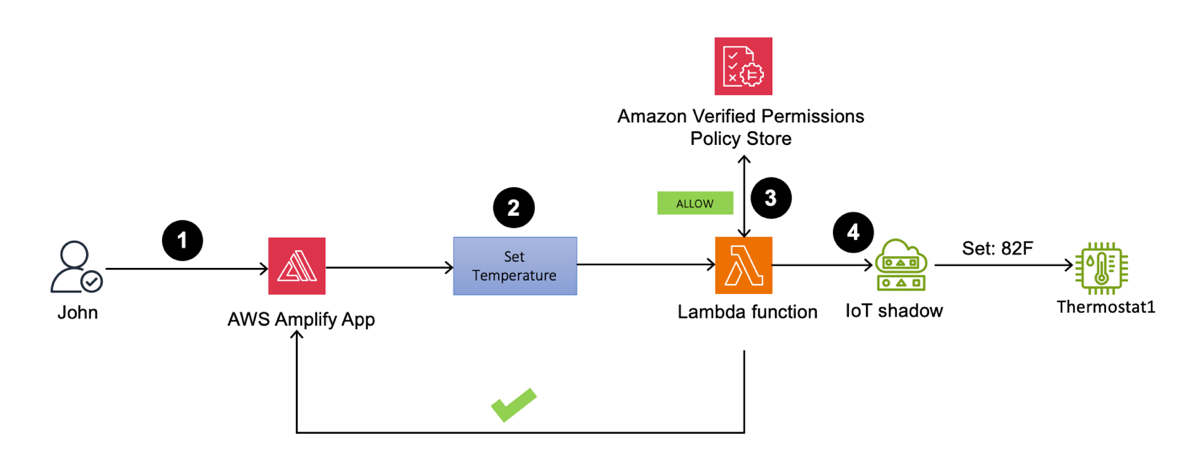
Primary owner signs in to the web application to set Thermostat1 temperature to 82°F

Figure 21: Thermostat1 temperature update by John

Figure 21: Thermostat1 temperature update by John

  1. Sign in to the Amplify web application as John. You should be able to view the Thermostat1 controller on the dashboard.
  2. Set the temperature to 82°F.
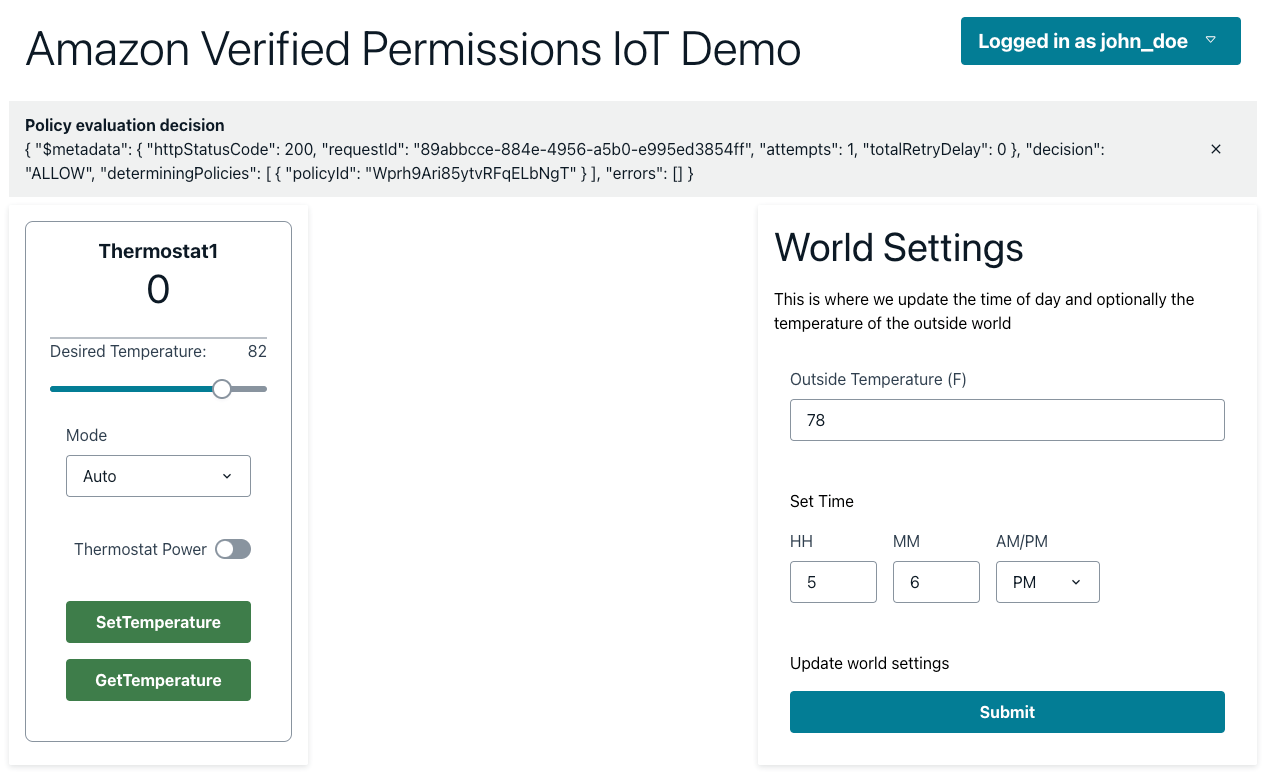
  3. The Lambda function processes the request and performs an API call to Verified Permissions to determine whether to ALLOW or DENY the action based on the policies. Verified Permissions sends back an ALLOW, as the policy that was previously set up allows unrestricted access for primary owners.
  4. Upon receiving the response from Verified Permissions, the Lambda function sends ALLOW permission back to the web application and an API call to the AWS IoT Device Shadow service to update the device (Thermostat1) temperature to 82°F.
     
Figure 22: Policy evaluation decision is ALLOW when a primary owner calls SetTemperature

Figure 22: Policy evaluation decision is ALLOW when a primary owner calls SetTemperature

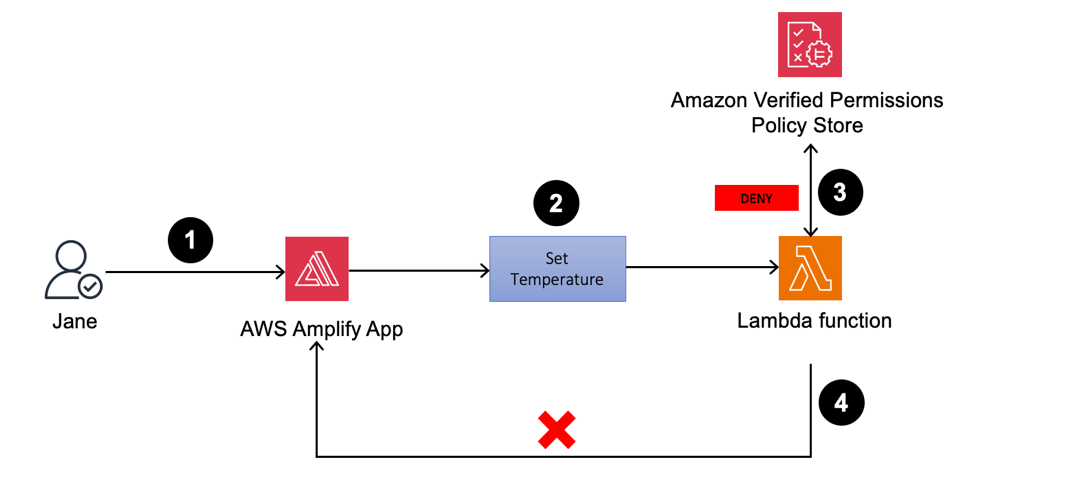
Guest user signs in to the web application to set Thermostat1 temperature to 80°F

Figure 23: Thermostat1 temperature update by Jane

Figure 23: Thermostat1 temperature update by Jane

  1. If you sign in as Jane to the Amplify web application, you can view the Thermostat1 controller on the dashboard.
  2. Set the temperature to 80°F.
  3. The Lambda function validates the actions by sending an API call to Verified Permissions to determine whether to ALLOW or DENY the action based on the established policies. Verified Permissions sends back a DENY, as the policy only permits temperature adjustments between 72°F and 78°F.
  4. Upon receiving the response from Verified Permissions, the Lambda function sends DENY permissions back to the web application and an unauthorized response is returned.
     
    Figure 24: Guest user jane_doe receives a DENY when calling SetTemperature for a desired temperature of 80°F

    Figure 24: Guest user jane_doe receives a DENY when calling SetTemperature for a desired temperature of 80°F

  5. If you repeat the process (still as Jane) but set Thermostat1 to 75°F, the policy will cause the request to be allowed.
     
    Figure 25: Guest user jane_doe receives an ALLOW when calling SetTemperature for a desired temperature of 75°F

    Figure 25: Guest user jane_doe receives an ALLOW when calling SetTemperature for a desired temperature of 75°F

  6. Similarly, jane_doe is allowed run GetTemperature on the device Thermostat1. When the temperature is set to 74°F, the device shadow is updated. The IoT device being simulated by your AWS Cloud9 instance reads desired the temperature field and sets the reported value to 74.
  7. Now, when jane_doe runs GetTemperature, the value of the device is reported as 74 as shown in Figure 26. We encourage you to try different restrictions in the World Settings (outside temperature and time) by adding restrictions to the static policy that allows GetTemperature for guest user.
     
    Figure 26: Guest user jane_doe receives an ALLOW when calling GetTemperature for the reported temperature

    Figure 26: Guest user jane_doe receives an ALLOW when calling GetTemperature for the reported temperature

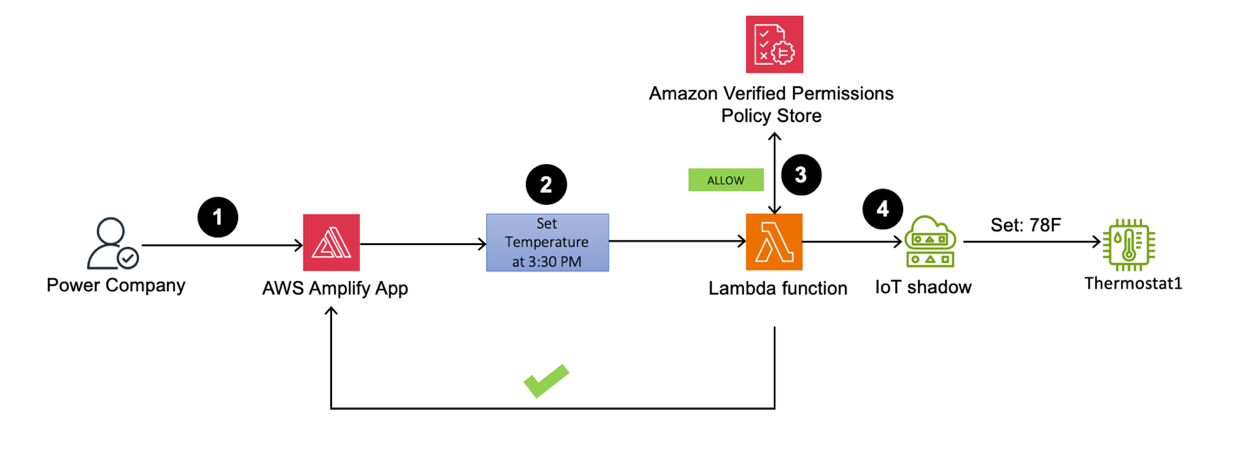
Power company signs in to the web application to set Thermostat1 to 78°F at 3.30 PM

Figure 27: Thermostat1 temperature set to 78°F by powercompany user at a specified time

Figure 27: Thermostat1 temperature set to 78°F by powercompany user at a specified time

  1. Sign in as the powercompany user to the Amplify web application using an API. You can view the Thermostat1 controller on the dashboard.
  2. To test this scenario, set the current time to 3:30 PM, and try to set the temperature to 78°F.
  3. The Lambda function validates the actions by sending an API call to Verified Permissions to determine whether to ALLOW or DENY the action based on pre-established policies. Verified Permissions returns ALLOW permission, because the policy for powercompany permits device temperature changes between 2:00 PM and 5:00 PM.
  4. Upon receiving the response from Verified Permissions, the Lambda function sends ALLOW permission back to the web application and an API call to the AWS IoT Device Shadow service to update the Thermostat1 temperature to 78°F.
     
    Figure 28: powercompany receives an ALLOW when SetTemperature is called with the desired temperature of 78°F

    Figure 28: powercompany receives an ALLOW when SetTemperature is called with the desired temperature of 78°F

Note: As an optional exercise, we also made jane_doe a device owner for device Thermostat2. This can be observed in the users.json file in the Github repository. We encourage you to create your own policies and restrict functions for Thermostat2 after going through this post. You will need to create separate Verified Permissions policies and update the Lambda functions to interact with these policies.

We encourage you to create policies for guests and the power company and restrict permissions based on the following criteria:

  1. Verify Jane Doe can perform GetTemperature and SetTemperature actions on Thermostat2.
  2. John Doe should not be able to set the temperature on device Thermostat2 outside of the time range of 4:00 PM and 6:00 PM and outside of the temperature range of 68°F and 72°F.
  3. Power Company can only perform the GetTemperature operation, but there are no restrictions on time and outside temperature.

To help you verify the solution, we’ve provided the correct policies under the challenge directory in the GitHub repository.

Clean up

Deploying the Thermostat application in your AWS account will incur costs. To avoid ongoing charges, when you’re done examining the solution, delete the resources that were created. This includes the Amplify hosted web application, API Gateway resource, AWS Cloud 9 environment, the Lambda function, DynamoDB table, Cognito user pool, AWS IoT Core resources, and Verified Permissions policy store.

Amplify resources can be deleted by going to the AWS CloudFormation console and deleting the stacks that were used to provision various services.

Conclusion

In this post, you learned about creating and managing fine-grained permissions using Verified Permissions for different user personas for your smart thermostat IoT device. With Verified Permissions, you can strengthen your security posture and build smart applications aligned with Zero Trust principles for real-time authorization decisions. To learn more, we recommend:

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Author

Rajat Mathur

Rajat is a Principal Solutions Architect at Amazon Web Services. Rajat is a passionate technologist who enjoys building innovative solutions for AWS customers. His core areas of focus are IoT, Networking, and Serverless computing. In his spare time, Rajat enjoys long drives, traveling, and spending time with family.

Pronoy Chopra

Pronoy Chopra

Pronoy is a Senior Solutions Architect with the Startups Generative AI team at AWS. He specializes in architecting and developing IoT and Machine Learning solutions. He has co-founded two startups and enjoys being hands-on with projects in the IoT, AI/ML and Serverless domain. His work in Magnetoencephalography has been cited many times in the effort to build better brain-compute interfaces.

Syed Sanoor

Syed Sanoor

Syed serves as a Solutions Architect, assisting customers in the enterprise sector. With a foundation in software engineering, he takes pleasure in crafting solutions tailored to client needs. His expertise predominantly lies in C# and IoT. During his leisure time, Syed enjoys piloting drones and playing cricket.

Serverless ICYMI Q1 2024

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/serverless-icymi-q1-2024/

Welcome to the 25th edition of the AWS Serverless ICYMI (in case you missed it) quarterly recap. Every quarter, we share all the most recent product launches, feature enhancements, blog posts, webinars, live streams, and other interesting things that you might have missed!

In case you missed our last ICYMI, check out what happened last quarter here.

2024 Q1 calendar

2024 Q1 calendar

Adobe Summit

At the Adobe Summit, the AWS Serverless Developer Advocacy team showcased a solution developed for the NFL using AWS serverless technologies and Adobe Photoshop APIs. The system automates image processing tasks, including background removal and dynamic resizing, by integrating AWS Step Functions, AWS Lambda, Amazon EventBridge, and AI/ML capabilities via Amazon Rekognition. This solution reduced image processing time from weeks to minutes and saved the NFL significant costs. Combining cloud-based serverless architectures with advanced machine learning and API technologies can optimize digital workflows for cost-effective and agile digital asset management.

Adobe Summit ServerlessVideo

Adobe Summit ServerlessVideo

ServerlessVideo is a demo application to stream live videos and also perform advanced post-video processing. It uses several AWS services, including Step Functions, Lambda, EventBridge, Amazon ECS, and Amazon Bedrock in a serverless architecture that makes it fast, flexible, and cost-effective. The team used ServerlessVideo to interview attendees about the conference experience and Adobe and partners about how they use Adobe. Learn more about the project and watch videos from Adobe Summit 2024 at video.serverlessland.com.

AWS Lambda

AWS launched support for the latest long-term support release of .NET 8, which includes API enhancements, improved Native Ahead of Time (Native AOT) support, and improved performance.

AWS Lambda .NET 8

AWS Lambda .NET 8

Learn how to compare design approaches for building serverless microservices. This post covers the trade-offs to consider with various application architectures. See how you can apply single responsibility, Lambda-lith, and read and write functions.

The AWS Serverless Java Container has been updated. This makes it easier to modernize a legacy Java application written with frameworks such as Spring, Spring Boot, or JAX-RS/Jersey in Lambda with minimal code changes.

AWS Serverless Java Container

AWS Serverless Java Container

Lambda has improved the responsiveness for configuring Event Source Mappings (ESMs) and Amazon EventBridge Pipes with event sources such as self-managed Apache Kafka, Amazon Managed Streaming for Apache Kafka (MSK), Amazon DocumentDB, and Amazon MQ.

Chaos engineering is a popular practice for building confidence in system resilience. However, many existing tools assume the ability to alter infrastructure configurations, and cannot be easily applied to the serverless application paradigm. You can use the AWS Fault Injection Service (FIS) to automate and manage chaos experiments across different Lambda functions to provide a reusable testing method.

Amazon ECS and AWS Fargate

Amazon Elastic Container Service (Amazon ECS) now provides managed instance draining as a built-in feature of Amazon ECS capacity providers. This allows Amazon ECS to safely and automatically drain tasks from Amazon Elastic Compute Cloud (Amazon EC2) instances that are part of an Amazon EC2 Auto Scaling Group associated with an Amazon ECS capacity provider. This simplification allows you to remove custom lifecycle hooks previously used to drain Amazon EC2 instances. You can now perform infrastructure updates such as rolling out a new version of the ECS agent by seamlessly using Auto Scaling Group instance refresh, with Amazon ECS ensuring workloads are not interrupted.

Credentials Fetcher makes it easier to run containers that depend on Windows authentication when using Amazon EC2. Credentials Fetcher now integrates with Amazon ECS, using either the Amazon EC2 launch type, or AWS Fargate serverless compute launch type.

Amazon ECS Service Connect is a networking capability to simplify service discovery, connectivity, and traffic observability for Amazon ECS. You can now more easily integrate certificate management to encrypt service-to-service communication using Transport Layer Security (TLS). You do not need to modify your application code, add additional network infrastructure, or operate service mesh solutions.

Amazon ECS Service Connect

Amazon ECS Service Connect

Running distributed machine learning (ML) workloads on Amazon ECS allows ML teams to focus on creating, training and deploying models, rather than spending time managing the container orchestration engine. Amazon ECS provides a great environment to run ML projects as it supports workloads that use NVIDIA GPUs and provides optimized images with pre-installed NVIDIA Kernel drivers and Docker runtime.

See how to build preview environments for Amazon ECS applications with AWS Copilot. AWS Copilot is an open source command line interface that makes it easier to build, release, and operate production ready containerized applications.

Learn techniques for automatic scaling of your Amazon Elastic Container Service  (Amazon ECS) container workloads to enhance the end user experience. This post explains how to use AWS Application Auto Scaling which helps you configure automatic scaling of your Amazon ECS service. You can also use Amazon ECS Service Connect and AWS Distro for OpenTelemetry (ADOT) in Application Auto Scaling.

AWS Step Functions

AWS workloads sometimes require access to data stored in on-premises databases and storage locations. Traditional solutions to establish connectivity to the on-premises resources require inbound rules to firewalls, a VPN tunnel, or public endpoints. Discover how to use the MQTT protocol (AWS IoT Core) with AWS Step Functions to dispatch jobs to on-premises workers to access or retrieve data stored on-premises.

You can use Step Functions to orchestrate many business processes. Many industries are required to provide audit trails for decision and transactional systems. Learn how to build a serverless pipeline to create a reliable, performant, traceable, and durable pipeline for audit processing.

Amazon EventBridge

Amazon EventBridge now supports publishing events to AWS AppSync GraphQL APIs as native targets. The new integration allows you to publish events easily to a wider variety of consumers and simplifies updating clients with near real-time data.

Amazon EventBridge publishing events to AWS AppSync

Amazon EventBridge publishing events to AWS AppSync

Discover how to send and receive CloudEvents with EventBridge. CloudEvents is an open-source specification for describing event data in a common way. You can publish CloudEvents directly to EventBridge, filter and route them, and use input transformers and API Destinations to send CloudEvents to downstream AWS services and third-party APIs.

AWS Application Composer

AWS Application Composer lets you create infrastructure as code templates by dragging and dropping cards on a virtual canvas. These represent CloudFormation resources, which you can wire together to create permissions and references. Application Composer has now expanded to the VS Code IDE as part of the AWS Toolkit. This now includes a generative AI partner that helps you write infrastructure as code (IaC) for all 1100+ AWS CloudFormation resources that Application Composer now supports.

AWS AppComposer generate suggestions

AWS AppComposer generate suggestions

Amazon API Gateway

Learn how to consume private Amazon API Gateway APIs using mutual TLS (mTLS). mTLS helps prevent man-in-the-middle attacks and protects against threats such as impersonation attempts, data interception, and tampering.

Serverless at AWS re:Invent

Serverless at AWS reInvent

Serverless at AWS reInvent

Visit the Serverless Land YouTube channel to find a list of serverless and serverless container sessions from reinvent 2023. Hear from experts like Chris Munns and Julian Wood in their popular session, Best practices for serverless developers, or Nathan Peck and Jessica Deen in Deploying multi-tenant SaaS applications on Amazon ECS and AWS Fargate.

Serverless blog posts

January

February

March

Serverless container blog posts

January

February

December

Serverless Office Hours

Serverless Office Hours

Serverless Office Hours

January

February

March

Containers from the Couch

Containers from the Couch

Containers from the Couch

January

February

March

FooBar Serverless

FooBar Serverless

FooBar Serverless

January

February

March

Still looking for more?

The Serverless landing page has more information. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.

You can also follow the Serverless Developer Advocacy team on Twitter to see the latest news, follow conversations, and interact with the team.

And finally, visit the Serverless Land and Containers on AWS websites for all your serverless and serverless container needs.

Automating chaos experiments with AWS Fault Injection Service and AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/automating-chaos-experiments-with-aws-fault-injection-service-and-aws-lambda/

This post is written by André Stoll, Solution Architect.

Chaos engineering is a popular practice for building confidence in system resilience. However, many existing tools assume the ability to alter infrastructure configurations, and cannot be easily applied to the serverless application paradigm. Due to the stateless, ephemeral, and distributed nature of serverless architectures, you must evolve the traditional technique when running chaos experiments on these systems.

This blog post explains a technique for running chaos engineering experiments on AWS Lambda functions. The approach uses Lambda extensions to induce failures in a runtime-agnostic way requiring no function code changes. It shows how you can use the AWS Fault Injection Service (FIS) to automate and manage chaos experiments across different Lambda functions to provide a reusable testing method.

Overview

Chaos experiments are commonly applied to cloud applications to uncover latent issues and prevent service disruptions. IT teams use chaos experiments to build confidence in the robustness of their systems. However, the traditional methods used in server-based chaos engineering do not easily translate to the serverless world since many existing tools are based on altering the underlying infrastructure configurations, such as cluster nodes or server instances of your applications.

In serverless applications, AWS handles the undifferentiated heavy lifting of managing infrastructure, so you can focus on delivering business value. But this also means that engineering teams have limited control over the infrastructure, and must rely on application-level tooling to run chaos experiments. Two techniques commonly used in the serverless community for conducting chaos experiments on Lambda functions are modifying the function configuration or using runtime-specific libraries.

Changing the configuration of a Lambda function allows you to induce rudimentary failures. For example, you can set the reserved concurrency of a Lambda function to simulate invocation throttling. Alternatively, you might change the function execution role permissions or the function policy to simulate IAM access denial. These types of failures are easy to implement, but the range of possible fault injection types is limited.

The other technique—injecting chaos into Lambda functions through purpose-built, runtime-specific libraries—is more flexible. There are various open-source libraries that allow you to inject failures, such as added latency, exceptions, or disk exhaustion. Examples of such libraries are Python’s chaos_lambda and failure-lambda for Node.js. The downside is that you must change the function code for every function you want to run chaos experiments on. In addition, those libraries are runtime-specific and each library comes with a set of different capabilities and configurations. This reduces the reusability of your chaos experiments across Lambda functions implemented in different languages.

Injecting chaos using Lambda extensions

Implementing chaos experiments using Lambda extensions allows you to address all of the previous concerns. Lambda extensions augment your functions by adding functionality, such as capturing diagnostic information or automatically instrumenting your code. You can integrate your preferred monitoring, observability, or security tooling deeply into the Lambda environment without complex installation or configuration management. Lambda extensions are generally packaged as Lambda layers and run as a separate process in the Lambda execution environment. You may use extensions from AWS, AWS Lambda partners, or build your own custom functionality.

With Lambda extensions, you can implement a chaos extension to inject the desired failures into your Lambda environments. This chaos extension uses the Runtime API proxy pattern that enables you to hook into the function invocation request and response lifecycle. Lambda runtimes use the Lambda Runtime API to retrieve the next incoming event to be processed by the function handler and return the handler response to the Lambda service.

The Runtime API HTTP endpoint is available within the Lambda execution environment. Runtimes get the API endpoint from the environment variable AWS_LAMBDA_RUNTIME_API. During the initialization of the execution environment, you can modify the runtime startup behavior. This lets you change the value of AWS_LAMBDA_RUNTIME_API to the port the chaos extension process is listening on. Now, all requests to the Runtime API go through the chaos extension proxy. You can use this workflow for blocking malicious events, auditing payloads, or injecting failures.

Injecting chaos using Lambda extensions

  1. The chaos extension intercepts incoming events and outbound responses, and injects failures according to the chaos experiment configuration.
  2. The extension accesses environment variables to read the chaos experiment configuration.
  3. A wrapper script configures the runtime to proxy requests through the chaos extension.

When intercepting incoming events and outbound responses to the Lambda Runtime API, you can simulate failures such as introducing artificial delay or generate an error response to return to the Lambda service. This workflow adds latency to your function calls:

Workflow

All Lambda runtimes support extensions. Since extensions run as a separate process, you can implement them in a language other than the function code. AWS recommends you implement extensions using a programming language that compiles to a binary executable, such as Golang or Rust. This allows you to use the extension with any Lambda runtime.

Some of the open source projects following this technique are the chaos-lambda-extension, implemented in Rust, or the serverless-chaos-extension, implemented in Python.

Extensions provide you with a flexible and reusable method to run your chaos experiments on Lambda functions. You can reuse the chaos extension for all runtimes without having to change function code. Add the extension to any Lambda function where you want to run chaos experiments.

Automating with AWS FIS experiment templates

According to the Principles of Chaos Engineering, you should “automate your experiments to run continuously”. To achieve this, you can use the AWS Fault Injection Service (FIS).

This service allows you to generate reusable experiment templates. The template specifies the targets and the actions to run on them during the experiment, and an optional stop condition that prevents the experiment from going out of bounds. You can also execute AWS Systems Manager Automation runbooks which support custom fault types. You can write your own custom Systems Manager documents to define the individual steps involved in the automation. To carry out the actions of the experiment, you define scripts in the document to manage your Lambda function and set it up for the chaos experiment.

To use the chaos extension for your serverless chaos experiments:

  1. Set up the Lambda function for the experiment. Add the chaos extension as a layer and configure the experiment, for example, by adding environment variables specifying the fault type and its corresponding value.
  2. Pause the automation and conduct the experiment. To do this, use the aws:sleep automation action. During this period, you conduct the experiment, measure and observe the outcome.
  3. Clean up the experiment. The script removes the layer again and also resets the environment variables.

Running your first serverless chaos experiment

This sample repository provides you with the necessary code to run your first serverless chaos experiment in AWS. The experiment uses the chaos-lambda-extension extension to inject chaos.

The sample deploys the AWS FIS experiment template, the necessary SSM Automation runbooks including the IAM role used by the runbook to configure the Lambda functions. The sample also provisions a Lambda function for testing and an Amazon CloudWatch alarm used to roll back the experiment.

Prerequisites

Running the experiment

Follow the steps outlined in the repository to conduct your first experiment. Starting the experiment triggers the automation execution.

Actions summary

This automation includes adding the extension and configuring the experiment, pausing the execution and observing the system and reverting all changes to the initial state.

Executed steps

If you invoke the targeted Lambda function during the second step, failures (in this case, artificial latency) are simulated.

Output result

Security best practices

Extensions run within the same execution environment as the function, so they have the same level of access to resources such as file system, networking, and environment variables. IAM permissions assigned to the function are shared with extensions. AWS recommends you assign the least required privileges to your functions.

Always install extensions from a trusted source only. Use Infrastructure as Code (IaC) and automation tools, such as CloudFormation or AWS Systems Manager, to simplify attaching the same extension configuration, including AWS Identity and Access Management (IAM) permissions, to multiple functions. IaC and automation tools allow you to have an audit record of extensions and versions used previously.

When building extensions, do not log sensitive data. Sanitize payloads and metadata before logging or persisting them for audit purposes.

Conclusion

This blog post details how to run chaos experiments for serverless applications built using Lambda. The described approach uses Lambda extension to inject faults into the execution environment. This allows you to use the same method regardless of runtime or configuration of the Lambda function.

To automate and successfully conduct the experiment, you can use the AWS Fault Injection Service. By creating an experiment template, you can specify the actions to run on the defined targets, such as adding the extension during the experiment. Since the extension can be used for any runtime, you can reuse the experiment template to inject failures into different Lambda functions.

Visit this repository to deploy your first serverless chaos experiment, or watch this video guide for learning more about building extensions. Explore the AWS FIS documentation to learn how to create your own experiments.

For more serverless learning resources, visit Serverless Land.

Sending and receiving CloudEvents with Amazon EventBridge

Post Syndicated from David Boyne original https://aws.amazon.com/blogs/compute/sending-and-receiving-cloudevents-with-amazon-eventbridge/

Amazon EventBridge helps developers build event-driven architectures (EDA) by connecting loosely coupled publishers and consumers using event routing, filtering, and transformation. CloudEvents is an open-source specification for describing event data in a common way. Developers can publish CloudEvents directly to EventBridge, filter and route them, and use input transformers and API Destinations to send CloudEvents to downstream AWS services and third-party APIs.

Overview

Event design is an important aspect in any event-driven architecture. Developers building event-driven architectures often overlook the event design process when building their architectures. This leads to unwanted side effects like exposing implementation details, lack of standards, and version incompatibility.

Without event standards, it can be difficult to integrate events or streams of messages between systems, brokers, and organizations. Each system has to understand the event structure or rely on custom-built solutions for versioning or validation.

CloudEvents is a specification for describing event data in common formats to provide interoperability between services, platforms, and systems using Cloud Native Computing Foundation (CNCF) projects. As CloudEvents is a CNCF graduated project, many third-party brokers and systems adopt this specification.

Using CloudEvents as a standard format to describe events makes integration easier and you can use open-source tooling to help build event-driven architectures and future proof any integrations. EventBridge can route and filter CloudEvents based on common metadata, without needing to understand the business logic within the event itself.

CloudEvents support two implementation modes, structured mode and binary mode, and a range of protocols including HTTP, MQTT, AMQP, and Kafka. When publishing events to an EventBridge bus, you can structure events as CloudEvents and route them to downstream consumers. You can use input transformers to transform any event into the CloudEvents specification. Events can also be forwarded to public APIs, using EventBridge API destinations, which supports both structured and binary mode encodings, enhancing interoperability with external systems.

Standardizing events using Amazon EventBridge

When publishing events to an EventBridge bus, EventBridge uses its own event envelope and represents events as JSON objects. EventBridge requires that you define top-level fields, such as detail-type and source. You can use any event/payload in the detail field.

This example event shows an OrderPlaced event from the orders-service that is unstructured without any event standards. The data within the event contains the order_id, customer_id and order_total.

{
  "version": "0",
  "id": "dbc1c73a-c51d-0c0e-ca61-ab9278974c57",
  "account": "1234567890",
  "time": "2023-05-23T11:38:46Z",
  "region": "us-east-1",
  "detail-type": "OrderPlaced",
  "source": "myapp.orders-service",
  "resources": [],
  "detail": {
    "data": {
      "order_id": "c172a984-3ae5-43dc-8c3f-be080141845a",
      "customer_id": "dda98122-b511-4aaf-9465-77ca4a115ee6",
      "order_total": "120.00"
    }
  }
}

Publishers may also choose to add an additional metadata field along with the data field within the detail field to help define a set of standards for their events.

{
  "version": "0",
  "id": "dbc1c73a-c51d-0c0e-ca61-ab9278974c58",
  "account": "1234567890",
  "time": "2023-05-23T12:38:46Z",
  "region": "us-east-1",
  "detail-type": "OrderPlaced",
  "source": "myapp.orders-service",
  "resources": [],
  "detail": {
    "metadata": {
      "idempotency_key": "29d2b068-f9c7-42a0-91e3-5ba515de5dbe",
      "correlation_id": "dddd9340-135a-c8c6-95c2-41fb8f492222",
      "domain": "ORDERS",
      "time": "1707908605"
    },
    "data": {
      "order_id": "c172a984-3ae5-43dc-8c3f-be080141845a",
      "customer_id": "dda98122-b511-4aaf-9465-77ca4a115ee6",
      "order_total": "120.00"
    }
  }
}

This additional event information helps downstream consumers, improves debugging, and can manage idempotency. While this approach offers practical benefits, it duplicates solutions that are already solved with the CloudEvents specification.

Publishing CloudEvents using Amazon EventBridge

When publishing events to EventBridge, you can use CloudEvents structured mode. A structured-mode message is where the entire event (attributes and data) is encoded in the message body, according to a specific event format. A binary-mode message is where the event data is stored in the message body, and event attributes are stored as part of the message metadata.

CloudEvents has a list of required fields but also offers flexibility with optional attributes and extensions. CloudEvents also offers a solution to implement idempotency, requiring that the combination of id and source must uniquely identify an event, which can be used as the idempotency key in downstream implementations.

{
  "version": "0",
  "id": "dbc1c73a-c51d-0c0e-ca61-ab9278974c58",
  "account": "1234567890",
  "time": "2023-05-23T12:38:46Z",
  "region": "us-east-1",
  "detail-type": "OrderPlaced",
  "source": "myapp.orders-service",
  "resources": [],
  "detail": {
    "specversion": "1.0",
    "id": "bba4379f-b764-4d90-9fb2-9f572b2b0b61",
    "source": "myapp.orders-service",
    "type": "OrderPlaced",
    "data": {
      "order_id": "c172a984-3ae5-43dc-8c3f-be080141845a",
      "customer_id": "dda98122-b511-4aaf-9465-77ca4a115ee6",
      "order_total": "120.00"
    },
    "time": "2024-01-01T17:31:00Z",
    "dataschema": "https://us-west-2.console.aws.amazon.com/events/home?region=us-west-2#/registries/discovered-schemas/schemas/myapp.orders-service%40OrderPlaced",
    "correlationid": "dddd9340-135a-c8c6-95c2-41fb8f492222",
    "domain": "ORDERS"
  }
}

By incorporating the required fields, the OrderPlaced event is now CloudEvents compliant. The event also contains optional and extension fields for additional information. Optional fields such as dataschema can be useful for brokers and consumers to retrieve a URI path to the published event schema. This example event references the schema in the EventBridge schema registry, so downstream consumers can fetch the schema to validate the payload.

Mapping existing events into CloudEvents using input transformers

When you define a target in EventBridge, input transformations allow you to modify the event before it reaches its destination. Input transformers are configured per target, allowing you to convert events when your downstream consumer requires the CloudEvents format and you want to avoid duplicating information.

Input transformers allow you to map EventBridge fields, such as id, region, detail-type, and source, into corresponding CloudEvents attributes.

This example shows how to transform any EventBridge event into CloudEvents format using input transformers, so the target receives the required structure.

{
  "version": "0",
  "id": "dbc1c73a-c51d-0c0e-ca61-ab9278974c58",
  "account": "1234567890",
  "time": "2024-01-23T12:38:46Z",
  "region": "us-east-1",
  "detail-type": "OrderPlaced",
  "source": "myapp.orders-service",
  "resources": [],
  "detail": {
    "order_id": "c172a984-3ae5-43dc-8c3f-be080141845a",
    "customer_id": "dda98122-b511-4aaf-9465-77ca4a115ee6",
    "order_total": "120.00"
  }
}

Using this input transformer and input template EventBridge transforms the event schema into the CloudEvents specification for downstream consumers.

Input transformer for CloudEvents:

{
  "id": "$.id",
  "source": "$.source",
  "type": "$.detail-type",
  "time": "$.time",
  "data": "$.detail"
}

Input template for CloudEvents:

{
  "specversion": "1.0",
  "id": "<id>",
  "source": "<source>",
  "type": "<type>",
  "time": "<time>",
  "data": <data>
}

This example shows the event payload that is received by downstream targets, which is mapped to the CloudEvents specification.

{
  "specversion": "1.0",
  "id": "dbc1c73a-c51d-0c0e-ca61-ab9278974c58",
  "source": "myapp.orders-service",
  "type": "OrderPlaced",
  "time": "2024-01-23T12:38:46Z",
  "data": {
      "order_id": "c172a984-3ae5-43dc-8c3f-be080141845a",
      "customer_id": "dda98122-b511-4aaf-9465-77ca4a115ee6",
      "order_total": "120.00"
    }
}

For more information on using input transformers with CloudEvents, see this pattern on Serverless Land.

Transforming events into CloudEvents using API destinations

EventBridge API destinations allows you to trigger HTTP endpoints based on matched rules to integrate with third-party systems using public APIs. You can route events to APIs that support the CloudEvents format by using input transformations and custom HTTP headers to convert EventBridge events to CloudEvents. API destinations now supports custom content-type headers. This allows you to send structured or binary CloudEvents to downstream consumers.

Sending binary CloudEvents using API destinations

When sending binary CloudEvents over HTTP, you must use the HTTP binding specification and set the necessary CloudEvents headers. These headers tell the downstream consumer that the incoming payload uses the CloudEvents format. The body of the request is the event itself.

CloudEvents headers are prefixed with ce-. You can find the list of headers in the HTTP protocol binding documentation.

This example shows the Headers for a binary event:

POST /order HTTP/1.1 
Host: webhook.example.com
ce-specversion: 1.0
ce-type: OrderPlaced
ce-source: myapp.orders-service
ce-id: bba4379f-b764-4d90-9fb2-9f572b2b0b61
ce-time: 2024-01-01T17:31:00Z
ce-dataschema: https://us-west-2.console.aws.amazon.com/events/home?region=us-west-2#/registries/discovered-schemas/schemas/myapp.orders-service%40OrderPlaced
correlationid: dddd9340-135a-c8c6-95c2-41fb8f492222
domain: ORDERS
Content-Type: application/json; charset=utf-8

This example shows the body for a binary event:

{
  "order_id": "c172a984-3ae5-43dc-8c3f-be080141845a",
  "customer_id": "dda98122-b511-4aaf-9465-77ca4a115ee6",
  "order_total": "120.00"
}

For more information when using binary CloudEvents with API destinations, explore this pattern available on Serverless Land.

Sending structured CloudEvents using API destinations

To support structured mode with CloudEvents, you must specify the content-type as application/cloudevents+json; charset=UTF-8, which tells the API consumer that the payload of the event is adhering to the CloudEvents specification.

POST /order HTTP/1.1
Host: webhook.example.com
 
Content-Type: application/cloudevents+json; charset=utf-8
{
    "specversion": "1.0",
    "id": "bba4379f-b764-4d90-9fb2-9f572b2b0b61",
    "source": "myapp.orders-service",
    "type": "OrderPlaced",      
    "data": {
      "order_id": "c172a984-3ae5-43dc-8c3f-be080141845a",
      "customer_id": "dda98122-b511-4aaf-9465-77ca4a115ee6",
      "order_total": "120.00"
    },
    "time": "2024-01-01T17:31:00Z",
    "dataschema": "https://us-west-2.console.aws.amazon.com/events/home?region=us-west-2#/registries/discovered-schemas/schemas/myapp.orders-service%40OrderPlaced",
    "correlationid": "dddd9340-135a-c8c6-95c2-41fb8f492222",
    "domain":"ORDERS"
}

Conclusion

Carefully designing events plays an important role when building event-driven architectures to integrate producers and consumers effectively. The open-source CloudEvents specification helps developers to standardize integration processes, simplifying interactions between internal systems and external partners.

EventBridge allows you to use a flexible payload structure within an event’s detail property to standardize events. You can publish structured CloudEvents directly onto an event bus in the detail field and use payload transformations to allow downstream consumers to receive events in the CloudEvents format.

EventBridge simplifies integration with third-party systems using API destinations. Using the new custom content-type headers with input transformers to modify the event structure, you can send structured or binary CloudEvents to integrate with public APIs.

For more serverless learning resources, visit Serverless Land.

How the GoDaddy data platform achieved over 60% cost reduction and 50% performance boost by adopting Amazon EMR Serverless

Post Syndicated from Brandon Abear original https://aws.amazon.com/blogs/big-data/how-the-godaddy-data-platform-achieved-over-60-cost-reduction-and-50-performance-boost-by-adopting-amazon-emr-serverless/

This is a guest post co-written with Brandon Abear, Dinesh Sharma, John Bush, and Ozcan IIikhan from GoDaddy.

GoDaddy empowers everyday entrepreneurs by providing all the help and tools to succeed online. With more than 20 million customers worldwide, GoDaddy is the place people come to name their ideas, build a professional website, attract customers, and manage their work.

At GoDaddy, we take pride in being a data-driven company. Our relentless pursuit of valuable insights from data fuels our business decisions and ensures customer satisfaction. Our commitment to efficiency is unwavering, and we’ve undertaken an exciting initiative to optimize our batch processing jobs. In this journey, we have identified a structured approach that we refer to as the seven layers of improvement opportunities. This methodology has become our guide in the pursuit of efficiency.

In this post, we discuss how we enhanced operational efficiency with Amazon EMR Serverless. We share our benchmarking results and methodology, and insights into the cost-effectiveness of EMR Serverless vs. fixed capacity Amazon EMR on EC2 transient clusters on our data workflows orchestrated using Amazon Managed Workflows for Apache Airflow (Amazon MWAA). We share our strategy for the adoption of EMR Serverless in areas where it excels. Our findings reveal significant benefits, including over 60% cost reduction, 50% faster Spark workloads, a remarkable five-times improvement in development and testing speed, and a significant reduction in our carbon footprint.

Background

In late 2020, GoDaddy’s data platform initiated its AWS Cloud journey, migrating an 800-node Hadoop cluster with 2.5 PB of data from its data center to EMR on EC2. This lift-and-shift approach facilitated a direct comparison between on-premises and cloud environments, ensuring a smooth transition to AWS pipelines, minimizing data validation issues and migration delays.

By early 2022, we successfully migrated our big data workloads to EMR on EC2. Using best practices learned from the AWS FinHack program, we fine-tuned resource-intensive jobs, converted Pig and Hive jobs to Spark, and reduced our batch workload spend by 22.75% in 2022. However, scalability challenges emerged due to the multitude of jobs. This prompted GoDaddy to embark on a systematic optimization journey, establishing a foundation for more sustainable and efficient big data processing.

Seven layers of improvement opportunities

In our quest for operational efficiency, we have identified seven distinct layers of opportunities for optimization within our batch processing jobs, as shown in the following figure. These layers range from precise code-level enhancements to more comprehensive platform improvements. This multi-layered approach has become our strategic blueprint in the ongoing pursuit of better performance and higher efficiency.

Seven layers of improvement opportunities

The layers are as follows:

  • Code optimization – Focuses on refining the code logic and how it can be optimized for better performance. This involves performance enhancements through selective caching, partition and projection pruning, join optimizations, and other job-specific tuning. Using AI coding solutions is also an integral part of this process.
  • Software updates – Updating to the latest versions of open source software (OSS) to capitalize on new features and improvements. For example, Adaptive Query Execution in Spark 3 brings significant performance and cost improvements.
  • Custom Spark configurations – Tuning of custom Spark configurations to maximize resource utilization, memory, and parallelism. We can achieve significant improvements by right-sizing tasks, such as through spark.sql.shuffle.partitions, spark.sql.files.maxPartitionBytes, spark.executor.cores, and spark.executor.memory. However, these custom configurations might be counterproductive if they are not compatible with the specific Spark version.
  • Resource provisioning time – The time it takes to launch resources like ephemeral EMR clusters on Amazon Elastic Compute Cloud (Amazon EC2). Although some factors influencing this time are outside of an engineer’s control, identifying and addressing the factors that can be optimized can help reduce overall provisioning time.
  • Fine-grained scaling at task level – Dynamically adjusting resources such as CPU, memory, disk, and network bandwidth based on each stage’s needs within a task. The aim here is to avoid fixed cluster sizes that could result in resource waste.
  • Fine-grained scaling across multiple tasks in a workflow – Given that each task has unique resource requirements, maintaining a fixed resource size may result in under- or over-provisioning for certain tasks within the same workflow. Traditionally, the size of the largest task determines the cluster size for a multi-task workflow. However, dynamically adjusting resources across multiple tasks and steps within a workflow result in a more cost-effective implementation.
  • Platform-level enhancements – Enhancements at preceding layers can only optimize a given job or a workflow. Platform improvement aims to attain efficiency at the company level. We can achieve this through various means, such as updating or upgrading the core infrastructure, introducing new frameworks, allocating appropriate resources for each job profile, balancing service usage, optimizing the use of Savings Plans and Spot Instances, or implementing other comprehensive changes to boost efficiency across all tasks and workflows.

Layers 1–3: Previous cost reductions

After we migrated from on premises to AWS Cloud, we primarily focused our cost-optimization efforts on the first three layers shown in the diagram. By transitioning our most costly legacy Pig and Hive pipelines to Spark and optimizing Spark configurations for Amazon EMR, we achieved significant cost savings.

For example, a legacy Pig job took 10 hours to complete and ranked among the top 10 most expensive EMR jobs. Upon reviewing TEZ logs and cluster metrics, we discovered that the cluster was vastly over-provisioned for the data volume being processed and remained under-utilized for most of the runtime. Transitioning from Pig to Spark was more efficient. Although no automated tools were available for the conversion, manual optimizations were made, including:

  • Reduced unnecessary disk writes, saving serialization and deserialization time (Layer 1)
  • Replaced Airflow task parallelization with Spark, simplifying the Airflow DAG (Layer 1)
  • Eliminated redundant Spark transformations (Layer 1)
  • Upgraded from Spark 2 to 3, using Adaptive Query Execution (Layer 2)
  • Addressed skewed joins and optimized smaller dimension tables (Layer 3)

As a result, job cost decreased by 95%, and job completion time was reduced to 1 hour. However, this approach was labor-intensive and not scalable for numerous jobs.

Layers 4–6: Find and adopt the right compute solution

In late 2022, following our significant accomplishments in optimization at the previous levels, our attention moved towards enhancing the remaining layers.

Understanding the state of our batch processing

We use Amazon MWAA to orchestrate our data workflows in the cloud at scale. Apache Airflow is an open source tool used to programmatically author, schedule, and monitor sequences of processes and tasks referred to as workflows. In this post, the terms workflow and job are used interchangeably, referring to the Directed Acyclic Graphs (DAGs) consisting of tasks orchestrated by Amazon MWAA. For each workflow, we have sequential or parallel tasks, and even a combination of both in the DAG between create_emr and terminate_emr tasks running on a transient EMR cluster with fixed compute capacity throughout the workflow run. Even after optimizing a portion of our workload, we still had numerous non-optimized workflows that were under-utilized due to over-provisioning of compute resources based on the most resource-intensive task in the workflow, as shown in the following figure.

This highlighted the impracticality of static resource allocation and led us to recognize the necessity of a dynamic resource allocation (DRA) system. Before proposing a solution, we gathered extensive data to thoroughly understand our batch processing. Analyzing the cluster step time, excluding provisioning and idle time, revealed significant insights: a right-skewed distribution with over half of the workflows completing in 20 minutes or less and only 10% taking more than 60 minutes. This distribution guided our choice of a fast-provisioning compute solution, dramatically reducing workflow runtimes. The following diagram illustrates step times (excluding provisioning and idle time) of EMR on EC2 transient clusters in one of our batch processing accounts.

Furthermore, based on the step time (excluding provisioning and idle time) distribution of the workflows, we categorized our workflows into three groups:

  • Quick run – Lasting 20 minutes or less
  • Medium run – Lasting between 20–60 minutes
  • Long run – Exceeding 60 minutes, often spanning several hours or more

Another factor we needed to consider was the extensive use of transient clusters for reasons such as security, job and cost isolation, and purpose-built clusters. Additionally, there was a significant variation in resource needs between peak hours and periods of low utilization.

Instead of fixed-size clusters, we could potentially use managed scaling on EMR on EC2 to achieve some cost benefits. However, migrating to EMR Serverless appears to be a more strategic direction for our data platform. In addition to potential cost benefits, EMR Serverless offers additional advantages such as a one-click upgrade to the newest Amazon EMR versions, a simplified operational and debugging experience, and automatic upgrades to the latest generations upon rollout. These features collectively simplify the process of operating a platform on a larger scale.

Evaluating EMR Serverless: A case study at GoDaddy

EMR Serverless is a serverless option in Amazon EMR that eliminates the complexities of configuring, managing, and scaling clusters when running big data frameworks like Apache Spark and Apache Hive. With EMR Serverless, businesses can enjoy numerous benefits, including cost-effectiveness, faster provisioning, simplified developer experience, and improved resilience to Availability Zone failures.

Recognizing the potential of EMR Serverless, we conducted an in-depth benchmark study using real production workflows. The study aimed to assess EMR Serverless performance and efficiency while also creating an adoption plan for large-scale implementation. The findings were highly encouraging, showing EMR Serverless can effectively handle our workloads.

Benchmarking methodology

We split our data workflows into three categories based on total step time (excluding provisioning and idle time): quick run (0–20 minutes), medium run (20–60 minutes), and long run (over 60 minutes). We analyzed the impact of the EMR deployment type (Amazon EC2 vs. EMR Serverless) on two key metrics: cost-efficiency and total runtime speedup, which served as our overall evaluation criteria. Although we did not formally measure ease of use and resiliency, these factors were considered throughout the evaluation process.

The high-level steps to assess the environment are as follows:

  1. Prepare the data and environment:
    1. Choose three to five random production jobs from each job category.
    2. Implement required adjustments to prevent interference with production.
  2. Run tests:
    1. Run scripts over several days or through multiple iterations to gather precise and consistent data points.
    2. Perform tests using EMR on EC2 and EMR Serverless.
  3. Validate data and test runs:
    1. Validate input and output datasets, partitions, and row counts to ensure identical data processing.
  4. Gather metrics and analyze results:
    1. Gather relevant metrics from the tests.
    2. Analyze results to draw insights and conclusions.

Benchmark results

Our benchmark results showed significant enhancements across all three job categories for both runtime speedup and cost-efficiency. The improvements were most pronounced for quick jobs, directly resulting from faster startup times. For instance, a 20-minute (including cluster provisioning and shut down) data workflow running on an EMR on EC2 transient cluster of fixed compute capacity finishes in 10 minutes on EMR Serverless, providing a shorter runtime with cost benefits. Overall, the shift to EMR Serverless delivered substantial performance improvements and cost reductions at scale across job brackets, as seen in the following figure.

Historically, we devoted more time to tuning our long-run workflows. Interestingly, we discovered that the existing custom Spark configurations for these jobs did not always translate well to EMR Serverless. In cases where the results were insignificant, a common approach was to discard previous Spark configurations related to executor cores. By allowing EMR Serverless to autonomously manage these Spark configurations, we often observed improved outcomes. The following graph shows the average runtime and cost improvement per job when comparing EMR Serverless to EMR on EC2.

Per Job Improvement

The following table shows a sample comparison of results for the same workflow running on different deployment options of Amazon EMR (EMR on EC2 and EMR Serverless).

Metric EMR on EC2
(Average)
EMR Serverless
(Average)
EMR on EC2 vs
EMR Serverless
Total Run Cost ($) $ 5.82 $ 2.60 55%
Total Run Time (Minutes) 53.40 39.40 26%
Provisioning Time (Minutes) 10.20 0.05 .
Provisioning Cost ($) $ 1.19 . .
Steps Time (Minutes) 38.20 39.16 -3%
Steps Cost ($) $ 4.30 . .
Idle Time (Minutes) 4.80 . .
EMR Release Label emr-6.9.0 .
Hadoop Distribution Amazon 3.3.3 .
Spark Version Spark 3.3.0 .
Hive/HCatalog Version Hive 3.1.3, HCatalog 3.1.3 .
Job Type Spark .

AWS Graviton2 on EMR Serverless performance evaluation

After seeing compelling results with EMR Serverless for our workloads, we decided to further analyze the performance of the AWS Graviton2 (arm64) architecture within EMR Serverless. AWS had benchmarked Spark workloads on Graviton2 EMR Serverless using the TPC-DS 3TB scale, showing a 27% overall price-performance improvement.

To better understand the integration benefits, we ran our own study using GoDaddy’s production workloads on a daily schedule and observed an impressive 23.8% price-performance enhancement across a range of jobs when using Graviton2. For more details about this study, see GoDaddy benchmarking results in up to 24% better price-performance for their Spark workloads with AWS Graviton2 on Amazon EMR Serverless.

Adoption strategy for EMR Serverless

We strategically implemented a phased rollout of EMR Serverless via deployment rings, enabling systematic integration. This gradual approach let us validate improvements and halt further adoption of EMR Serverless, if needed. It served both as a safety net to catch issues early and a means to refine our infrastructure. The process mitigated change impact through smooth operations while building team expertise of our Data Engineering and DevOps teams. Additionally, it fostered tight feedback loops, allowing prompt adjustments and ensuring efficient EMR Serverless integration.

We divided our workflows into three main adoption groups, as shown in the following image:

  • Canaries – This group aids in detecting and resolving any potential problems early in the deployment stage.
  • Early adopters – This is the second batch of workflows that adopt the new compute solution after initial issues have been identified and rectified by the canaries group.
  • Broad deployment rings – The largest group of rings, this group represents the wide-scale deployment of the solution. These are deployed after successful testing and implementation in the previous two groups.

Rings

We further broke down these workflows into granular deployment rings to adopt EMR Serverless, as shown in the following table.

Ring # Name Details
Ring 0 Canary Low adoption risk jobs that are expected to yield some cost saving benefits.
Ring 1 Early Adopters Low risk Quick-run Spark jobs that expect to yield high gains.
Ring 2 Quick-run Rest of the Quick-run (step_time <= 20 min) Spark jobs
Ring 3 LargerJobs_EZ High potential gain, easy move, medium-run and long-run Spark jobs
Ring 4 LargerJobs Rest of the medium-run and long-run Spark jobs with potential gains
Ring 5 Hive Hive jobs with potentially higher cost savings
Ring 6 Redshift_EZ Easy migration Redshift jobs that suit EMR Serverless
Ring 7 Glue_EZ Easy migration Glue jobs that suit EMR Serverless

Production adoption results summary

The encouraging benchmarking and canary adoption results generated considerable interest in wider EMR Serverless adoption at GoDaddy. To date, the EMR Serverless rollout remains underway. Thus far, it has reduced costs by 62.5% and accelerated total batch workflow completion by 50.4%.

Based on preliminary benchmarks, our team expected substantial gains for quick jobs. To our surprise, actual production deployments surpassed projections, averaging 64.4% faster vs. 42% projected, and 71.8% cheaper vs. 40% predicted.

Remarkably, long-running jobs also saw significant performance improvements due to the rapid provisioning of EMR Serverless and aggressive scaling enabled by dynamic resource allocation. We observed substantial parallelization during high-resource segments, resulting in a 40.5% faster total runtime compared to traditional approaches. The following chart illustrates the average enhancements per job category.

Prod Jobs Savings

Additionally, we observed the highest degree of dispersion for speed improvements within the long-run job category, as shown in the following box-and-whisker plot.

Whisker Plot

Sample workflows adopted EMR Serverless

For a large workflow migrated to EMR Serverless, comparing 3-week averages pre- and post-migration revealed impressive cost savings—a 75.30% decrease based on retail pricing with 10% improvement in total runtime, boosting operational efficiency. The following graph illustrates the cost trend.

Although quick-run jobs realized minimal per-dollar cost reductions, they delivered the most significant percentage cost savings. With thousands of these workflows running daily, the accumulated savings are substantial. The following graph shows the cost trend for a small workload migrated from EMR on EC2 to EMR Serverless. Comparing 3-week pre- and post-migration averages revealed a remarkable 92.43% cost savings on the retail on-demand pricing, alongside an 80.6% acceleration in total runtime.

Sample workflows adopted EMR Serverless 2

Layer 7: Platform-wide improvements

We aim to revolutionize compute operations at GoDaddy, providing simplified yet powerful solutions for all users with our Intelligent Compute Platform. With AWS compute solutions like EMR Serverless and EMR on EC2, it provided optimized runs of data processing and machine learning (ML) workloads. An ML-powered job broker intelligently determines when and how to run jobs based on various parameters, while still allowing power users to customize. Additionally, an ML-powered compute resource manager pre-provisions resources based on load and historical data, providing efficient, fast provisioning at optimum cost. Intelligent compute empowers users with out-of-the-box optimization, catering to diverse personas without compromising power users.

The following diagram shows a high-level illustration of the intelligent compute architecture.

Insights and recommended best-practices

The following section discusses the insights we’ve gathered and the recommended best practices we’ve developed during our preliminary and wider adoption stages.

Infrastructure preparation

Although EMR Serverless is a deployment method within EMR, it requires some infrastructure preparedness to optimize its potential. Consider the following requirements and practical guidance on implementation:

  • Use large subnets across multiple Availability Zones – When running EMR Serverless workloads within your VPC, make sure the subnets span across multiple Availability Zones and are not constrained by IP addresses. Refer to Configuring VPC access and Best practices for subnet planning for details.
  • Modify maximum concurrent vCPU quota – For extensive compute requirements, it is recommended to increase your max concurrent vCPUs per account service quota.
  • Amazon MWAA version compatibility – When adopting EMR Serverless, GoDaddy’s decentralized Amazon MWAA ecosystem for data pipeline orchestration created compatibility issues from disparate AWS Providers versions. Directly upgrading Amazon MWAA was more efficient than updating numerous DAGs. We facilitated adoption by upgrading Amazon MWAA instances ourselves, documenting issues, and sharing findings and effort estimates for accurate upgrade planning.
  • GoDaddy EMR operator – To streamline migrating numerous Airflow DAGs from EMR on EC2 to EMR Serverless, we developed custom operators adapting existing interfaces. This allowed seamless transitions while retaining familiar tuning options. Data engineers could easily migrate pipelines with simple find-replace imports and immediately use EMR Serverless.

Unexpected behavior mitigation

The following are unexpected behaviors we ran into and what we did to mitigate them:

  • Spark DRA aggressive scaling – For some jobs (8.33% of initial benchmarks, 13.6% of production), cost increased after migrating to EMR Serverless. This was due to Spark DRA excessively assigning new workers briefly, prioritizing performance over cost. To counteract this, we set maximum executor thresholds by adjusting spark.dynamicAllocation.maxExecutor, effectively limiting EMR Serverless scaling aggression. When migrating from EMR on EC2, we suggest observing the max core count in the Spark History UI to replicate similar compute limits in EMR Serverless, such as --conf spark.executor.cores and --conf spark.dynamicAllocation.maxExecutors.
  • Managing disk space for large-scale jobs – When transitioning jobs that process large data volumes with substantial shuffles and significant disk requirements to EMR Serverless, we recommend configuring spark.emr-serverless.executor.disk by referring to existing Spark job metrics. Furthermore, configurations like spark.executor.cores combined with spark.emr-serverless.executor.disk and spark.dynamicAllocation.maxExecutors allow control over the underlying worker size and total attached storage when advantageous. For example, a shuffle-heavy job with relatively low disk usage may benefit from using a larger worker to increase the likelihood of local shuffle fetches.

Conclusion

As discussed in this post, our experiences with adopting EMR Serverless on arm64 have been overwhelmingly positive. The impressive results we’ve achieved, including a 60% reduction in cost, 50% faster runs of batch Spark workloads, and an astounding five-times improvement in development and testing speed, speak volumes about the potential of this technology. Furthermore, our current results suggest that by widely adopting Graviton2 on EMR Serverless, we could potentially reduce the carbon footprint by up to 60% for our batch processing.

However, it’s crucial to understand that these results are not a one-size-fits-all scenario. The enhancements you can expect are subject to factors including, but not limited to, the specific nature of your workflows, cluster configurations, resource utilization levels, and fluctuations in computational capacity. Therefore, we strongly advocate for a data-driven, ring-based deployment strategy when considering the integration of EMR Serverless, which can help optimize its benefits to the fullest.

Special thanks to Mukul Sharma and Boris Berlin for their contributions to benchmarking. Many thanks to Travis Muhlestein (CDO), Abhijit Kundu (VP Eng), Vincent Yung (Sr. Director Eng.), and Wai Kin Lau (Sr. Director Data Eng.) for their continued support.


About the Authors

Brandon Abear is a Principal Data Engineer in the Data & Analytics (DnA) organization at GoDaddy. He enjoys all things big data. In his spare time, he enjoys traveling, watching movies, and playing rhythm games.

Dinesh Sharma is a Principal Data Engineer in the Data & Analytics (DnA) organization at GoDaddy. He is passionate about user experience and developer productivity, always looking for ways to optimize engineering processes and saving cost. In his spare time, he loves reading and is an avid manga fan.

John Bush is a Principal Software Engineer in the Data & Analytics (DnA) organization at GoDaddy. He is passionate about making it easier for organizations to manage data and use it to drive their businesses forward. In his spare time, he loves hiking, camping, and riding his ebike.

Ozcan Ilikhan is the Director of Engineering for the Data and ML Platform at GoDaddy. He has over two decades of multidisciplinary leadership experience, spanning startups to global enterprises. He has a passion for leveraging data and AI in creating solutions that delight customers, empower them to achieve more, and boost operational efficiency. Outside of his professional life, he enjoys reading, hiking, gardening, volunteering, and embarking on DIY projects.

Harsh Vardhan is an AWS Solutions Architect, specializing in big data and analytics. He has over 8 years of experience working in the field of big data and data science. He is passionate about helping customers adopt best practices and discover insights from their data.

AWS Weekly Roundup — Claude 3 Sonnet support in Bedrock, new instances, and more — March 11, 2024

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-3-sonnet-support-in-bedrock-new-instances-and-more-march-11-2024/

Last Friday was International Women’s Day (IWD), and I want to take a moment to appreciate the amazing ladies in the cloud computing space that are breaking the glass ceiling by reaching technical leadership positions and inspiring others to go and build, as our CTO Werner Vogels says.Now go build

Last week’s launches
Here are some launches that got my attention during the previous week.

Amazon Bedrock – Now supports Anthropic’s Claude 3 Sonnet foundational model. Claude 3 Sonnet is two times faster and has the same level of intelligence as Anthropic’s highest-performing models, Claude 2 and Claude 2.1. My favorite characteristic is that Sonnet is better at producing JSON outputs, making it simpler for developers to build applications. It also offers vision capabilities. You can learn more about this foundation model (FM) in the post that Channy wrote early last week.

AWS re:Post – Launched last week! AWS re:Post Live is a weekly Twitch livestream show that provides a way for the community to reach out to experts, ask questions, and improve their skills. The show livestreams every Monday at 11 AM PT.

Amazon CloudWatch – Now streams daily metrics on CloudWatch metric streams. You can use metric streams to send a stream of near real-time metrics to a destination of your choice.

Amazon Elastic Compute Cloud (Amazon EC2) – Announced the general availability of new metal instances, C7gd, M7gd, and R7gd. These instances have up to 3.8 TB of local NVMe-based SSD block-level storage and are built on top of the AWS Nitro System.

AWS WAF – Now supports configurable evaluation time windows for request aggregation with rate-based rules. Previously, AWS WAF was fixed to a 5-minute window when aggregating and evaluating the rules. Now you can select windows of 1, 2, 5 or 10 minutes, depending on your application use case.

AWS Partners – Last week, we announced the AWS Generative AI Competency Partners. This new specialization features AWS Partners that have shown technical proficiency and a track record of successful projects with generative artificial intelligence (AI) powered by AWS.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS news
Some other updates and news that you may have missed:

One of the articles that caught my attention recently compares different design approaches for building serverless microservices. This article, written by Luca Mezzalira and Matt Diamond, compares the three most common designs for serverless workloads and explains the benefits and challenges of using one over the other.

And if you are interested in the serverless space, you shouldn’t miss the Serverless Office Hours, which airs live every Tuesday at 10 AM PT. Join the AWS Serverless Developer Advocates for a weekly chat on the latest from the serverless space.

Serverless office hours

The Official AWS Podcast – Listen each week for updates on the latest AWS news and deep dives into exciting use cases. There are also official AWS podcasts in several languages. Check out the ones in French, German, Italian, and Spanish.

AWS Open Source News and Updates – This is a newsletter curated by my colleague Ricardo to bring you the latest open source projects, posts, events, and more.

Upcoming AWS events
Check your calendars and sign up for these AWS events:

AWS Summit season is about to start. The first ones are Paris (April 3), Amsterdam (April 9), and London (April 24). AWS Summits are free events that you can attend in person and learn about the latest in AWS technology.

GOTO x AWS EDA Day London 2024 – On May 14, AWS partners with GOTO bring to you the event-driven architecture (EDA) day conference. At this conference, you will get to meet experts in the EDA space and listen to very interesting talks from customers, experts, and AWS.

GOTO EDA Day 2022

You can browse all upcoming in-person and virtual events here.

That’s all for this week. Check back next Monday for another Week in Review!

— Marcia

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

In-stream anomaly detection with Amazon OpenSearch Ingestion and Amazon OpenSearch Serverless

Post Syndicated from Rupesh Tiwari original https://aws.amazon.com/blogs/big-data/in-stream-anomaly-detection-with-amazon-opensearch-ingestion-and-amazon-opensearch-serverless/

Unsupervised machine learning analytics has emerged as a powerful tool for anomaly detection in today’s data-rich landscape, especially with the growing volume of machine-generated data. In-stream anomaly detection offers real-time insights into data anomalies, enabling proactive response. Amazon OpenSearch Serverless focuses on delivering seamless scalability and management of search workloads; Amazon OpenSearch Ingestion complements this by providing a robust solution for anomaly detection on indexed data.

In this post, we provide a solution using OpenSearch Ingestion that empowers you to perform in-stream anomaly detection within your own AWS environment.

In-stream anomaly detection with OpenSearch Ingestion

OpenSearch Ingestion makes the process of in-stream anomaly detection straightforward and at less cost. In-stream anomaly detection helps you save on indexing and avoids the need for extensive resources to handle big data. It lets organizations apply the appropriate resources at the appropriate time, managing large data efficiently and saving money. Using peer forwarders and aggregate processors can make things more complex and expensive; OpenSearch Ingestion reduces these issues.

Let’s look at a use case showing an OpenSearch Ingestion configuration YAML for in-stream anomaly detection.

Solution overview

In this example, we walk through the setup of OpenSearch Ingestion using a random cut forest anomaly detector for monitoring log counts within a 5-minute period. We also index the raw logs to provide a comprehensive demonstration of the incoming data flow. If your use case requires the analysis of raw logs, you can streamline the process by bypassing the initial pipeline and focus directly on in-stream anomaly detection, indexing only the identified anomalies.

The following diagram illustrates our solution architecture.

The configuration outlines two OpenSearch Ingestion pipelines. The first, non-ad-pipeline, ingests HTTP data, timestamps it, and forwards it to both ad-pipeline and an OpenSearch index, non-ad-index. The second, ad-pipeline, receives this data, performs aggregation based on the ID within a 5-minute window, and conducts anomaly detection. Results are stored in the index ad-anomaly-index. This setup showcases data processing, anomaly detection, and storage within OpenSearch Service, enhancing analysis capabilities.

Implement the solution

Complete the following steps to set up the solution:

  1. Create a pipeline role.
  2. Create a collection.
  3. Create a pipeline in which you specify the pipeline role.

The pipeline assumes this role in order to sign requests to the OpenSearch Serverless collection endpoint. Specify the values for the keys within the following pipeline configuration:

  • For sts_role_arn, specify the Amazon Resource Name (ARN) of the pipeline role that you created.
  • For hosts, specify the endpoint of the collection that you created.
  • Set serverless to true.
version: "2"
# 1st pipeline
non-ad-pipeline:
  source:
    http:
      path: "/${pipelineName}/test_ingestion_path"
  processor:
    - date:
        from_time_received: true
        destination: "@timestamp"
  sink:
    - pipeline:
        name: "ad-pipeline"
    - opensearch:
        hosts:
          [
            "https://{collection-id}.us-east-1.aoss.amazonaws.com",
          ]
        index: "non-ad-index"
        
        aws:
          sts_role_arn: "arn:aws:iam::{account-id}:role/pipeline-role"
          region: "us-east-1"
          serverless: true
# 2nd pipeline
ad-pipeline:
  source:
    pipeline:
      name: "non-ad-pipeline"
  processor:
    - aggregate:
        identification_keys: ["id"]
        action:
          count:
        group_duration: "300s"
    - anomaly_detector:
        keys: ["value"] # value will have sum of logs
        mode:
          random_cut_forest:
            output_after: 200 
  sink:
    - opensearch:
        hosts:
          [
            "https://{collection-id}.us-east-1.aoss.amazonaws.com",
          ]
        aws:
          sts_role_arn: "arn:aws:iam::{account-id}:role/pipeline-role"
          region: "us-east-1"
          serverless: true
        index: "ad-anomaly-index"

For a detailed guide on the required parameters and any limitations, see Supported plugins and options for Amazon OpenSearch Ingestion pipelines.

  1. After you update the configuration, confirm the validity of your pipeline settings by choosing Validate pipeline.

A successful validation will display a message stating “Pipeline configuration validation successful.” as shown in the following screenshot.

If validation fails, refer to Troubleshooting Amazon OpenSearch Service for troubleshooting and guidance.

Cost estimation for OpenSearch Ingestion

You are only charged for the number of Ingestion OpenSearch Compute Units (Ingestion OCUs) that are allocated to a pipeline, regardless of whether there’s data flowing through the pipeline. OpenSearch Ingestion immediately accommodates your workloads by scaling pipeline capacity up or down based on usage. For an overview of expenses, refer to Amazon OpenSearch Ingestion.

The following table shows approximate monthly costs based on specified throughputs and compute needs. Let’s assume that operation occurs from 8:00 AM to 8:00 PM on weekdays, with a cost of $0.24 per OCU per hour.

The formula would be: Total Cost/Month = OCU Requirement * OCU Price * Hours/Day * Days/Month.

Throughput Compute Required (OCUs) Total Cost/Month (USD)
1 Gbps 10 576
10 Gbps 100 5760
50 Gbps 500 28800
100 Gbps 1000 57600
500 Gbps 5000 288000

Clean up

When you are done using the solution, delete the resources you created, including the pipeline role, pipeline, and collection.

Summary

With OpenSearch Ingestion, you can explore in-stream anomaly detection with OpenSearch Service. The use case in this post demonstrates how OpenSearch Ingestion simplifies the process, achieving more with fewer resources. It showcases the service’s ability to analyze log rates, generate anomaly notifications, and empower proactive response to anomalies. With OpenSearch Ingestion, you can improve operational efficiency and enhance real-time risk management capabilities.

Leave any thoughts and questions in the comments.


About the Authors

Rupesh Tiwari, an AWS Solutions Architect, specializes in modernizing applications with a focus on data analytics, OpenSearch, and generative AI. He’s known for creating scalable, secure solutions that leverage cloud technology for transformative business outcomes, also dedicating time to community engagement and sharing expertise.

Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

Building a Serverless Streaming Pipeline to Deliver Reliable Messaging

Post Syndicated from Chris McPeek original https://aws.amazon.com/blogs/compute/building-a-serverless-streaming-pipeline-to-deliver-reliable-messaging/

This post is written by Jeff Harman, Senior Prototyping Architect, Vaibhav Shah, Senior Solutions Architect and Erik Olsen, Senior Technical Account Manager.

Many industries are required to provide audit trails for decision and transactional systems. AI assisted decision making requires monitoring the full inputs to the decision system in near real time to prevent fraud, detect model drift, and discrimination. Modern systems often use a much wider array of inputs for decision making, including images, unstructured text, historical values, and other large data elements. These large data elements pose a challenge to traditional audit systems that deal with relatively small text messages in structured formats. This blog shows the use of serverless technology to create a reliable, performant, traceable, and durable streaming pipeline for audit processing.

Overview

Consider the following four requirements to develop an architecture for audit record ingestion:

  1. Audit record size: Store and manage large payloads (256k – 6 MB in size) that may be heterogeneous, including text, binary data, and references to other storage systems.
  2. Audit traceability: The data stored has full traceability of the payload and external processes to monitor the process via subscription-based events.
  3. High Performance: The time required for blocking writes to the system is limited to the time it takes to transmit the audit record over the network.
  4. High data durability: Once the system sends a payload receipt, the payload is at very low risk of loss because of system failures.

The following diagram shows an architecture that meets these requirements and models the flow of the audit record through the system.

The primary source of latency is the time it takes for an audit record to be transmitted across the network. Applications sending audit records make an API call to an Amazon API Gateway endpoint. An AWS Lambda function receives the message and an Amazon ElastiCache for Redis cluster provides a low latency initial storage mechanism for the audit record. Once the data is stored in ElastiCache, the AWS Step Functions workflow then orchestrates the communication and persistence functions.

Subscribers receive four Amazon Simple Notification Service (Amazon SNS) notifications pertaining to arrival and storage of the audit record payload, storage of the audit record metadata, and audit record archive completion. Users can subscribe an Amazon Simple Queue Service (SQS) queue to the SNS topic and use fan out mechanisms to achieve high reliability.

  1. The Ingest Message Lambda function sends an initial receipt notification
  2. The Message Archive Handler Lambda function notifies on storage of the audit record from ElastiCache to Amazon Simple Storage Service (Amazon S3)
  3. The Message Metadata Handler Lambda function notifies on storage of the message metadata into Amazon DynamoDB
  4. The Final State Aggregation Lambda function notifies that the audit record has been archived.

Any failure by the three fundamental processing steps: Ingestion, Data Archive, and Metadata Archive triggers a message in an SQS Dead Letter Queue (DLQ) which contains the original request and an explanation of the failure reason. Any failure in the Ingest Message function invokes the Ingest Message Failure function, which stores the original parameters to the S3 Failed Message Storage bucket for later analysis.

The Step Functions workflow provides orchestration and parallel path execution for the system. The detailed workflow below shows the execution flow and notification actions. The transformer steps convert the internal data structures into the format required for consumers.

Data structures

There are types three events and messages managed by this system:

  1. Incoming message: This is the message the producer sends to an API Gateway endpoint.
  2. Internal message: This event contains the message metadata allowing subsequent systems to understand the originating message producer context.
  3. Notification message: Messages that allow downstream subscribers to act based on the message.

Solution walkthrough

The message producer calls the API Gateway endpoint, which enforces the security requirements defined by the business. In this implementation, API Gateway uses an API key for providing more robust security. API Gateway also creates a security header for consumption by the Ingest Message Lambda function. API Gateway can be configured to enforce message format standards, see Use request validation in API Gateway for more information.

The Ingest Message Lambda function generates a message ID that tracks the message payload throughout its lifecycle. Then it stores the full message in the ElastiCache for Redis cache. The Ingest Message Lambda function generates an internal message with all the elements necessary as described above. Finally, the Lambda function handler code starts the Step Functions workflow with the internal message payload.

If the Ingest Message Lambda function fails for any reason, the Lambda function invokes the Ingestion Failure Handler Lambda function. This Lambda function writes any recoverable incoming message data to an S3 bucket and sends a notification on the Ingest Message dead letter queue.

The Step Functions workflow then runs three processes in parallel.

  • The Step Functions workflow triggers the Message Archive Data Handler Lambda function to persist message data from the ElastiCache cache to an S3 bucket. Once stored, the Lambda function returns the S3 bucket reference and state information. There are two options to remove the internal message from the cache. Remove the message from cache immediately before sending the internal message and updating the ElastiCache cache flag or wait for the ElastiCache lifecycle to remove a stale message from cache. This solution waits for the ElastiCache lifecycle to remove the message.
  • The workflow triggers the Message Metadata Handler Lambda function to write all message metadata and security information to DynamoDB. The Lambda function replies with the DynamoDB reference information.
  • Finally, the Step Functions workflow sends a message to the SNS topic to inform subscribers that the message has arrived and the data persistence processes have started.

After each of the Lambda functions’ processes complete, the Lambda function sends a notification to the SNS notification topic to alert subscribers that each action is complete. When both Message Metadata and Message Archive Lambda functions are done, the Final Aggregation function makes a final update to the metadata in DynamoDB to include S3 reference information and to remove the ElastiCache Redis reference.

Deploying the solution

Prerequisites:

  1. AWS Serverless Application Model (AWS SAM) is installed (see Getting started with AWS SAM)
  2. AWS User/Credentials with appropriate permissions to run AWS CloudFormation templates in the target AWS account
  3. Python 3.8 – 3.10
  4. The AWS SDK for Python (Boto3) is installed
  5. The requests python library is installed

The source code for this implementation can be found at  https://github.com/aws-samples/blog-serverless-reliable-messaging

Installing the Solution:

  1. Clone the git repository to a local directory
  2. git clone https://github.com/aws-samples/blog-serverless-reliable-messaging.git
  3. Change into the directory that was created by the clone operation, usually blog_serverless_reliable_messaging
  4. Execute the command: sam build
  5. Execute the command: sam deploy –-guided. You are asked to supply the following parameters:
    1. Stack Name: Name given to this deployment (example: serverless-streaming)
    2. AWS Region: Where to deploy (example: us-east-1)
    3. ElasticacheInstanceClass: EC2 cache instance type to use with (example: cache.t3.small)
    4. ElasticReplicaCount: How many replicas should be used with ElastiCache (recommended minimum: 2)
    5. ProjectName: Used for naming resources in account (example: serverless-streaming)
    6. MultiAZ: True/False if multiple Availability Zones should be used (recommend: True)
    7. The default parameters can be selected for the remainder of questions

Testing:

Once you have deployed the stack, you can test it through the API gateway endpoint with the API key that is referenced in the deployment output. There are two methods for retrieving the API key either via the AWS console (from the link provided in the output – ApiKeyConsole) or via the AWS CLI (from the AWS CLI reference in the output – APIKeyCLI).

You can test directly in the Lambda service console by invoking the ingest message function.

A test message is available at the root of the project test_message.json for direct Lambda function testing of the Ingest function.

  1. In the console navigate to the Lambda service
  2. From the list of available functions, select the “<project name> -IngestMessageFunction-xxxxx” function
  3. Under the “Function overview” select the “Test” tab
  4. Enter an event name of your choosing
  5. Copy and paste the contents of test_message.json into the “Event JSON” box
  6. Click “Save” then after it has saved, click the “Test”
  7. If successful, you should see something similar to the below in the details:
    {
    "isBase64Encoded": false,
    "statusCode": 200,
    "headers": {
    "Access-Control-Allow-Headers": "Content-Type",
    "Access-Control-Allow-Origin": "*",
    "Access-Control-Allow-Methods": "OPTIONS,POST"
    },
    "body": "{\"messageID\": \"XXXXXXXXXXXXXX\"}"
    }
  8. In the S3 bucket “<project name>-s3messagearchive-xxxxxx“, find the payload of the original json with a key based on the date and time of the script execution, e.g.: YEAR/MONTH/DAY/HOUR/MINUTE with a file name of the messageID
  9. In a DynamoDB table named metaDataTable, you should find a record with a messageID equal to the messageID from above that contains all of the metadata related to the payload

A python script is included with the code in the test_client folder

  1. Replace the <Your API key key here> and the <Your API Gateway URL here (IngestMessageApi)> values with the correct ones for your environment in the test_client.py file
  2. Execute the test script with Python 3.8 or higher with the requests package installed
    Example execution (from main directory of git clone):
    python3 -m pip install -r ./test_client/requirements.txt
    python3 ./test_client/test_client.py
  3. Successful output shows the messageID and the header JSON payload:
    {
    "messageID": " XXXXXXXXXXXXXX"
    }
  4. In the S3 bucket “<project name>-s3messagearchive-xxxxxx“, you should be able to find the payload of the original json with a key based on the date and time of the script execution, e.g.: YEAR/MONTH/DAY/HOUR/MINUTE with a file name of the messageID
  5. In a DynamoDB table named metaDataTable, you should find a record with a messageID equal to the messageID from above that contains all of the meta data related to the payload

Conclusion

This blog describes architectural patterns, messaging patterns, and data structures that support a highly reliable messaging system for large messages. The use of serverless services including Lambda functions, Step Functions, ElastiCache, DynamoDB, and S3 meet the requirements of modern audit systems to be scalable and reliable. The architecture shared in this blog post is suitable for a highly regulated environment to store and track messages that are larger than typical logging systems, records sized between 256k and 6MB. The architecture serves as a blueprint that can be extended and adapted to fit further serverless use cases.

For serverless learning resources, visit Serverless Land.
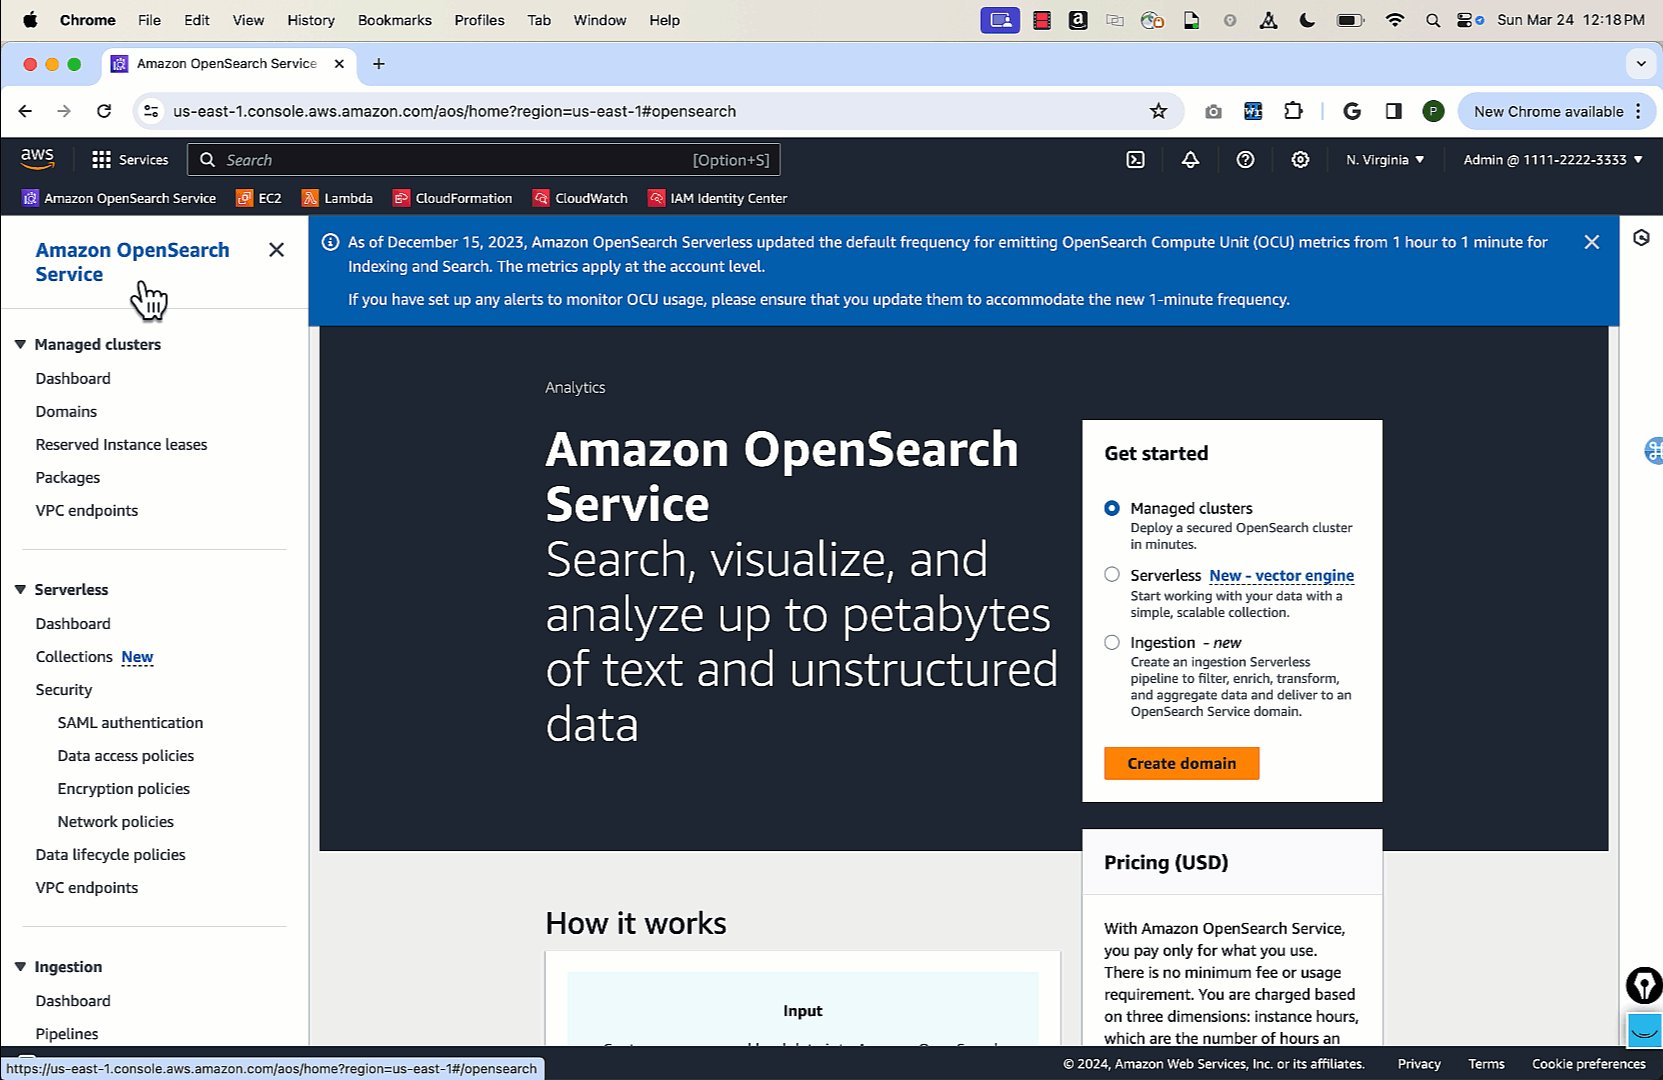
Comparing design approaches for building serverless microservices

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/comparing-design-approaches-for-building-serverless-microservices/

This post is written by Luca Mezzalira, Principal SA, and Matt Diamond, Principal, SA.

Designing a workload with AWS Lambda creates questions for developers due to the modularity that can be expressed either at the code or infrastructure level. Using serverless for running code requires additional planning to extract the business logic from the underlying functional components. This deliberate separation of concerns ensures a robust modularity, paving the way for evolutionary architectures.

This post focuses on synchronous workloads, but similar considerations are applicable in other workload types. After identifying the bounded context of your API and agreeing on API contracts with consumers, it’s time to structure the architecture of your bounded context and the associated infrastructure.

The two most common ways to structure an API using Lambda functions are single responsibility and Lambda-lith. However, this blog post explores an alternative to these approaches, which can provide the best of both.

Single responsibility Lambda functions

Single responsibility Lambda functions are designed to run a specific task or handle a particular event-triggered operation within a serverless architecture:

c:\temp\design1.png

This approach provides a strong separation of concerns between business logic and capabilities. You can test in isolation specific capabilities, deploy a Lambda function independently, reduce the surface to introduce bugs, and enable easier debugging for issues in Amazon CloudWatch.

Additionally, single purpose functions enable efficient resource allocation as Lambda automatically scales based on demand, optimizing resource consumption, and minimizing costs. This means you can modify the memory size, architecture, and any other configuration available per function. Moreover, requesting an update of concurrent function execution via a support ticket becomes easier because you are not aggregating the traffic to a single Lambda function that handles every request but you can request specific increase based on the traffic of a single task.

Another advantage is rapid execution time. Considering the business logic for a single-purpose Lambda function designed for a single task, you can optimize the size of a function more easily, without the need of additional libraries required in other approaches. This helps reduce the cold start time due to a smaller bundle size.

Despite these benefits, some issues exist when solely relying on single-purpose Lambda functions. While the cold start time is mitigated, you might experience a higher number of cold starts, particularly for functions with sporadic or infrequent invocations. For example, a function that deletes users in an Amazon DynamoDB table likely won’t be triggered as often as one that reads user data. Also, relying heavily on single-purpose Lambda functions can lead to increased system complexity, especially as the number of functions grows.

A good separation of concerns helps maintain your code base, at the cost of a lack of cohesion. In functions with similar tasks, such as write operations of an API (POST, PUT, DELETE), you might duplicate code and behaviors across multiple functions. Moreover, updating common libraries shared via Lambda Layers, or other dependency management systems, requires multiple changes across every function instead of an atomic change on a single file. This is also true for any other change across multiple functions, for instance, updating the runtime version.

Lambda-lith: Using one single Lambda function

When many workloads use single purpose Lambda functions, developers end up with a proliferation of Lambda functions across an AWS account. One of the main challenges developers face is updating common dependencies or function configurations. Unless there is a clear governance strategy implemented for addressing this problem (such as using Dependabot for enforcing the update of dependencies, or parameterized parameters that are retrieved at provisioning time), developers may opt for a different strategy.

As a result, many development teams move in the opposite direction, aggregating all code related to an API inside the same Lambda function.

Lambda-lith: Using one single Lambda function

This approach is often referred to as a Lambda-lith, because it gathers all the HTTP verbs that compose an API and sometimes multiple APIs in the same function.

This allows you to have a higher code cohesion and colocation across the different parts of the application. Modularity in this case is expressed at the code level, where patterns like single responsibility, dependency injection, and façade are applied to structure your code. The discipline and code best practices applied by the development teams is crucial for maintaining large code bases.

However, considering the reduced number of Lambda functions, updating a configuration or implementing a new standard across multiple APIs can be achieved more easily compared with the single responsibility approach.

Moreover, since every request invokes the same Lambda function for every HTTP verb, it’s more likely that little-used parts of your code have a better response time because an execution environment is more likely to be available to fulfill the request.

Another factor to consider is the function size. This increases when collocating verbs in the same function with all the dependencies and business logic of an API. This may affect the cold start of your Lambda functions with spiky workloads. Customers should evaluate the benefits of this approach, especially when applications have restrictive SLAs, which would be impacted by cold starts. Developers can mitigate this problem by paying attention to the dependencies used and implementing techniques like tree-shaking, minification, and dead code elimination, where the programming language allows.

This coarse grain approach won’t allow you to tune your function configurations individually. But you must find a configuration that matches all the code capabilities with a possibly higher memory size and looser security permissions that might clash with the requirements defined by the security team.

Read and write functions

These two approaches both have trade-offs, but there is a third option that can combine their benefits.

Often, API traffic leans towards more reads or writes and that forces developers to optimize code and configurations more on one side over the other.

For example, consider building a user API that allows consumers to create, update, and delete a user but also to find a user or a list of users. In this scenario, you can change one user at a time with no bulk operations available, but you can get one or more users per API request. Dividing the design of the API into read and write operations results in this architecture:

Read and write functions

The cohesion of code for write operations (create, update, and delete) is beneficial for many reasons. For instance, you may need to validate the request body, ensuring it contains all the mandatory parameters. If the workload is heavy on writes, the less-used operations (for instance, Delete) benefit from warm execution environments. The code colocation enables reusability of code on similar actions, reducing the cognitive load to structure your projects with shared libraries or Lambda layers, for instance.

When looking at the read operations side, you can reduce the code bundled with this function, having a faster cold start, and heavily optimize the performance compared to a write operation. You can also store partial or full query results in-memory of an execution environment to improve the execution time of a Lambda function.

This approach helps you further with its evolutionary nature. Imagine if this platform becomes much more popular. Now, you must optimize the API even further by improving reads and adding a cache aside pattern with ElastiCache and Redis. Moreover, you have decided to optimize the read queries with a second database that is optimized for the read capability when the cache is missed.

On the write side, you have agreed with the API consumers that receiving and acknowledging user creation or deletion is adequate, considering they fully embraced the eventual consistency nature of distributed systems.

Now, you can improve the response time of write operations by adding an SQS queue before the Lambda function. You can update the write database in batches to reduce the number of invocations needed for handling write operations, instead of dealing with every request individually.

CQRS pattern

Command query responsibility segregation (CQRS) is a well-established pattern that separates the data mutation, or the command part of a system, from the query part. You can use the CQRS pattern to separate updates and queries if they have different requirements for throughput, latency, or consistency.

While it’s not mandatory to start with a full CQRS pattern, you can evolve from the infrastructure highlighted more easily in the initial read and write implementation, without massive refactoring of your API.

Comparison of the three approaches

Here is a comparison of the three approaches:


Single responsibility Lambda-lith Read and write
Benefits
  • Strong separation of concerns
  • Granular configuration
  • Better debug
  • Rapid execution time
  • Fewer cold start invocations
  • Higher code cohesion
  • Simpler maintenance
  • Code cohesion where needed
  • Evolutionary architecture
  • Optimization of read and write operations
Issues
  • Code duplication
  • Complex maintenance
  • Higher cold start invocations
  • Corse grain configuration
  • Higher cold start time
  • Using CQRS with two data models
  • CQRS adds eventual consistency to your system

Conclusion

Developers often move from single responsibility functions to the Lambda-lith as their architectures evolve, but both approaches have relative trade-offs. This post shows how it’s possible to have the best of both approaches by dividing your workloads per read and write operations.

All three approaches are viable for designing serverless APIs, and understanding what you are optimizing for is the key for making the best decision. Remember, understanding your context and business requirements to express in your applications leads you towards the acceptable trade-offs to specify inside a specific workload. Keep an open mind and find the solution that solves the problem and balances security, developer experience, cost, and maintainability.

For more serverless learning resources, visit Serverless Land.

Top Architecture Blog Posts of 2023

Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2023/

2023 was a rollercoaster year in tech, and we at the AWS Architecture Blog feel so fortunate to have shared in the excitement. As we move into 2024 and all of the new technologies we could see, we want to take a moment to highlight the brightest stars from 2023.

As always, thanks to our readers and to the many talented and hardworking Solutions Architects and other contributors to our blog.

I give you our 2023 cream of the crop!

#10: Build a serverless retail solution for endless aisle on AWS

In this post, Sandeep and Shashank help retailers and their customers alike in this guided approach to finding inventory that doesn’t live on shelves.

Building endless aisle architecture for order processing

Figure 1. Building endless aisle architecture for order processing

Check it out!

#9: Optimizing data with automated intelligent document processing solutions

Who else dreads wading through large amounts of data in multiple formats? Just me? I didn’t think so. Using Amazon AI/ML and content-reading services, Deependra, Anirudha, Bhajandeep, and Senaka have created a solution that is scalable and cost-effective to help you extract the data you need and store it in a format that works for you.

AI-based intelligent document processing engine

Figure 2: AI-based intelligent document processing engine

Check it out!

#8: Disaster Recovery Solutions with AWS managed services, Part 3: Multi-Site Active/Passive

Disaster recovery posts are always popular, and this post by Brent and Dhruv is no exception. Their creative approach in part 3 of this series is most helpful for customers who have business-critical workloads with higher availability requirements.

Warm standby with managed services

Figure 3. Warm standby with managed services

Check it out!

#7: Simulating Kubernetes-workload AZ failures with AWS Fault Injection Simulator

Continuing with the theme of “when bad things happen,” we have Siva, Elamaran, and Re’s post about preparing for workload failures. If resiliency is a concern (and it really should be), the secret is test, test, TEST.

Architecture flow for Microservices to simulate a realistic failure scenario

Figure 4. Architecture flow for Microservices to simulate a realistic failure scenario

Check it out!

#6: Let’s Architect! Designing event-driven architectures

Luca, Laura, Vittorio, and Zamira weren’t content with their four top-10 spots last year – they’re back with some things you definitely need to know about event-driven architectures.

Let's Architect

Figure 5. Let’s Architect artwork

Check it out!

#5: Use a reusable ETL framework in your AWS lake house architecture

As your lake house increases in size and complexity, you could find yourself facing maintenance challenges, and Ashutosh and Prantik have a solution: frameworks! The reusable ETL template with AWS Glue templates might just save you a headache or three.

Reusable ETL framework architecture

Figure 6. Reusable ETL framework architecture

Check it out!

#4: Invoking asynchronous external APIs with AWS Step Functions

It’s possible that AWS’ menagerie of services doesn’t have everything you need to run your organization. (Possible, but not likely; we have a lot of amazing services.) If you are using third-party APIs, then Jorge, Hossam, and Shirisha’s architecture can help you maintain a secure, reliable, and cost-effective relationship among all involved.

Invoking Asynchronous External APIs architecture

Figure 7. Invoking Asynchronous External APIs architecture

Check it out!

#3: Announcing updates to the AWS Well-Architected Framework

The Well-Architected Framework continues to help AWS customers evaluate their architectures against its six pillars. They are constantly striving for improvement, and Haleh’s diligence in keeping us up to date has not gone unnoticed. Thank you, Haleh!

Well-Architected logo

Figure 8. Well-Architected logo

Check it out!

#2: Let’s Architect! Designing architectures for multi-tenancy

The practically award-winning Let’s Architect! series strikes again! This time, Luca, Laura, Vittorio, and Zamira were joined by Federica to discuss multi-tenancy and why that concept is so crucial for SaaS providers.

Let's Architect

Figure 9. Let’s Architect

Check it out!

And finally…

#1: Understand resiliency patterns and trade-offs to architect efficiently in the cloud

Haresh, Lewis, and Bonnie revamped this 2022 post into a masterpiece that completely stole our readers’ hearts and is among the top posts we’ve ever made!

Resilience patterns and trade-offs

Figure 10. Resilience patterns and trade-offs

Check it out!

Bonus! Three older special mentions

These three posts were published before 2023, but we think they deserve another round of applause because you, our readers, keep coming back to them.

Thanks again to everyone for their contributions during a wild year. We hope you’re looking forward to the rest of 2024 as much as we are!

Use Amazon OpenSearch Ingestion to migrate to Amazon OpenSearch Serverless

Post Syndicated from Muthu Pitchaimani original https://aws.amazon.com/blogs/big-data/use-amazon-opensearch-ingestion-to-migrate-to-amazon-opensearch-serverless/

Amazon OpenSearch Serverless is an on-demand auto scaling configuration for Amazon OpenSearch Service. Since its release, the interest for OpenSearch Serverless had been steadily growing. Customers prefer to let the service manage its capacity automatically rather than having to manually provision capacity. Until now, customers have had to rely on using custom code or third-party solutions to move the data between provisioned OpenSearch Service domains and OpenSearch Serverless.

We recently introduced a feature with Amazon OpenSearch Ingestion (OSI) to make this migration even more effortless. OSI is a fully managed, serverless data collector that delivers real-time log, metric, and trace data to OpenSearch Service domains and OpenSearch Serverless collections.

In this post, we outline the steps to make migrate the data between provisioned OpenSearch Service domains and OpenSearch Serverless. Migration of metadata such as security roles and dashboard objects will be covered in another subsequent post.

Solution overview

The following diagram shows the necessary components for moving data between OpenSearch Service provisioned domains and OpenSearch Serverless using OSI. You will use OSI with OpenSearch Service as source and an OpenSearch Serverless collection as sink.

Prerequisites

Before getting started, complete the following steps to create the necessary resources:

  1. Create an AWS Identity and Access Management (IAM) role that the OpenSearch Ingestion pipeline will assume to write to the OpenSearch Serverless collection. This role needs to be specified in the sts_role_arn parameter of the pipeline configuration.
  2. Attach a permissions policy to the role to allow it to read data from the OpenSearch Service domain. The following is a sample policy with least privileges:
    {
       "Version":"2012-10-17",
       "Statement":[
          {
             "Effect":"Allow",
             "Action":"es:ESHttpGet",
             "Resource":[
                "arn:aws:es:us-east-1:{account-id}:domain/{domain-name}/",
                "arn:aws:es:us-east-1:{account-id}:domain/{domain-name}/_cat/indices",
                "arn:aws:es:us-east-1:{account-id}:domain/{domain-name}/_search",
                "arn:aws:es:us-east-1:{account-id}:domain/{domain-name}/_search/scroll",
                "arn:aws:es:us-east-1:{account-id}:domain/{domain-name}/*/_search"
             ]
          },
          {
             "Effect":"Allow",
             "Action":"es:ESHttpPost",
             "Resource":[
                "arn:aws:es:us-east-1:{account-id}:domain/{domain-name}/*/_search/point_in_time",
                "arn:aws:es:us-east-1:{account-id}:domain/{domain-name}/*/_search/scroll"
             ]
          },
          {
             "Effect":"Allow",
             "Action":"es:ESHttpDelete",
             "Resource":[
                "arn:aws:es:us-east-1:{account-id}:domain/{domain-name}/_search/point_in_time",
                "arn:aws:es:us-east-1:{account-id}:domain/{domain-name}/_search/scroll"
             ]
          }
       ]
    }

  3. Attach a permissions policy to the role to allow it to send data to the collection. The following is a sample policy with least privileges:
    {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Action": [
            "aoss:BatchGetCollection",
            "aoss:APIAccessAll"
          ],
          "Effect": "Allow",
          "Resource": "arn:aws:aoss:{region}:{your-account-id}:collection/{collection-id}"
        },
        {
          "Action": [
            "aoss:CreateSecurityPolicy",
            "aoss:GetSecurityPolicy",
            "aoss:UpdateSecurityPolicy"
          ],
          "Effect": "Allow",
          "Resource": "*",
          "Condition": {
            "StringEquals": {
              "aoss:collection": "{collection-name}"
            }
          }
        }
      ]
    }

  4. Configure the role to assume the trust relationship, as follows:
    {
            "Version": "2012-10-17",
            "Statement": [
                {
                    "Effect": "Allow",
                    "Principal": {
                        "Service": "osis-pipelines.amazonaws.com"
                    },
                    "Action": "sts:AssumeRole"
                }
            ]
        }

  5. It’s recommended to add the aws:SourceAccount and aws:SourceArn condition keys to the policy for protection against the confused deputy problem:
    "Condition": {
        "StringEquals": {
            "aws:SourceAccount": "{your-account-id}"
        },
        "ArnLike": {
            "aws:SourceArn": "arn:aws:osis:{region}:{your-account-id}:pipeline/*"
        }
    }

  6. Map the OpenSearch Ingestion domain role ARN as a backend user (as an all_access user) to the domain user. We show a simplified example to use the all_access role. For production scenarios, make sure to use a role with just enough permissions to read and write.
  7. Create an OpenSearch Serverless collection, which is where data will be ingested.
  8. Associate a data policy, as shown in the following code, to grant the OpenSearch Ingestion role permissions on the collection:
    [
      {
        "Rules": [
          {
            "Resource": [
              "index/collection-name/*"
            ],
            "Permission": [
              "aoss:CreateIndex",
              "aoss:UpdateIndex",
              "aoss:DescribeIndex",
              "aoss:WriteDocument",
            ],
            "ResourceType": "index"
          }
        ],
        "Principal": [
          "arn:aws:iam::{account-id}:role/pipeline-role"
        ],
        "Description": "Pipeline role access"
      }
    ]

  9. If the collection is defined as a VPC collection, you need to create a network policy and configure it in the ingestion pipeline.

Now you’re ready to move data from your provisioned domain to OpenSearch Serverless.

Move data from provisioned domains to Serverless

Setup Amazon OpenSearch Ingestion
To get started, you must have an active OpenSearch Service domain (source) and OpenSearch Serverless collection (sink). Complete the following steps to set up an OpenSearch Ingestion pipeline for migration:

  1. On the OpenSearch Service console, choose Pipeline under Ingestion in the navigation pane.
  2. Choose Create a pipeline.
  3. For Pipeline name, enter a name (for example, octank-migration).
  4. For Pipeline capacity, you can define the minimum and maximum capacity to scale up the resources. For now, you can leave the default minimum as 1 and maximum as 4.
  5. For Configuration Blueprint, select AWS-OpenSearchDataMigrationPipeline.
  6. Update the following information for the source:
    1. Uncomment hosts and specify the endpoint of the existing OpenSearch Service endpoint.
    2. Uncomment distribution_version if your source cluster is an OpenSearch Service cluster with compatibility mode enabled; otherwise, leave it commented.
    3. Uncomment indices, include, index_name_regex, and add an index name or pattern that you want to migrate (for example, octank-iot-logs-2023.11.0*).
    4. Update region under aws where your source domain is (for example, us-west-2).
    5. Update sts_role_arn under aws to the role that has permission to read data from the OpenSearch Service domain (for example, arn:aws:iam::111122223333:role/osis-pipeline). This role should be added as a backend role within the OpenSearch Service security roles.
  7. Update the following information for the sink:
    1. Uncomment hosts and specify the endpoint of the existing OpenSearch Serverless endpoint.
    2. Update sts_role_arn under aws to the role that has permission to write data into the OpenSearch Serverless collection (for example, arn:aws:iam::111122223333:role/osis-pipeline). This role should be added as part of the data access policy in the OpenSearch Serverless collection.
    3. Update the serverless flag to be true.
    4. For index, you can leave it as default, which will get the metadata from the source index and write to the same name in the destination as of the sources. Alternatively, if you want to have a different index name at the destination, modify this value with your desired name.
    5. For document_id, you can get the ID from the document metadata in the source and use the same in the target. Note that custom document IDs are supported only for the SEARCH type of collection; if you have your collection as TIMESERIES or VECTORSEARCH, you should comment this line.
  8. Next, you can validate your pipeline to check the connectivity of source and sink to make sure the endpoint exists and is accessible.
  9. For Network settings, choose your preferred setting:
    1. Choose VPC access and select your VPC, subnet, and security group to set up the access privately.
    2. Choose Public to use public access. AWS recommends that you use a VPC endpoint for all production workloads, but this walkthrough, select Public.
  10. For Log Publishing Option, you can either create a new Amazon CloudWatch group or use an existing CloudWatch group to write the ingestion logs. This provides access to information about errors and warnings raised during the operation, which can help during troubleshooting. For this walkthrough, choose Create new group.
  11. Choose Next, and verify the details you specified for your pipeline settings.
  12. Choose Create pipeline.

It should take a couple of minutes to create the ingestion pipeline.
The following graphic gives a quick demonstration of creating the OpenSearch Ingestion pipeline via the preceding steps.

Verify ingested data in the target OpenSearch Serverless collection

After the pipeline is created and active, log in to OpenSearch Dashboards for your OpenSearch Serverless collection and run the following command to list the indexes:

GET _cat/indices?v

The following graphic gives a quick demonstration of listing the indexes before and after the pipeline becomes active.

Conclusion

In this post, we saw how OpenSearch Ingestion can ingest data into an OpenSearch Serverless collection without the need to use the third-party solutions. With minimal data producer configuration, it automatically ingested data to the collection. OSI also allows you to transform or reindex the data from ES7.x version before ingestion to an OpenSearch Service domain or OpenSearch Serverless collection. OSI eliminates the need to provision, scale, or manage servers. AWS offers various resources for you to quickly start building pipelines using OpenSearch Ingestion. You can use various built-in pipeline integrations to quickly ingest data from Amazon DynamoDB, Amazon Managed Streaming for Apache Kafka (Amazon MSK), Amazon Security Lake, Fluent Bit, and many more. The following OpenSearch Ingestion blueprints enable you to build data pipelines with minimal configuration changes.


About the Authors

Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

Prashant Agrawal is a Sr. Search Specialist Solutions Architect with Amazon OpenSearch Service. He works closely with customers to help them migrate their workloads to the cloud and helps existing customers fine-tune their clusters to achieve better performance and save on cost. Before joining AWS, he helped various customers use OpenSearch and Elasticsearch for their search and log analytics use cases. When not working, you can find him traveling and exploring new places. In short, he likes doing Eat → Travel → Repeat.

Rahul Sharma is a Technical Account Manager at Amazon Web Services. He is passionate about the data technologies that help leverage data as a strategic asset and is based out of New York city, New York.

Introducing the .NET 8 runtime for AWS Lambda

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/introducing-the-net-8-runtime-for-aws-lambda/

This post is written by Beau Gosse, Senior Software Engineer and Paras Jain, Senior Technical Account Manager.

AWS Lambda now supports .NET 8 as both a managed runtime and container base image. With this release, Lambda developers can benefit from .NET 8 features including API enhancements, improved Native Ahead of Time (Native AOT) support, and improved performance. .NET 8 supports C# 12, F# 8, and PowerShell 7.4. You can develop Lambda functions in .NET 8 using the AWS Toolkit for Visual Studio, the AWS Extensions for .NET CLI, AWS Serverless Application Model (AWS SAM), AWS CDK, and other infrastructure as code tools.

Creating .NET 8 function in the console

Creating .NET 8 function in the console

What’s new

Upgraded operating system

The .NET 8 runtime is built on the Amazon Linux 2023 (AL2023) minimal container image. This provides a smaller deployment footprint than earlier Amazon Linux 2 (AL2) based runtimes and updated versions of common libraries such as glibc 2.34 and OpenSSL 3.

The new image also uses microdnf as a package manager, symlinked as dnf. This replaces the yum package manager used in earlier AL2-based images. If you deploy your Lambda functions as container images, you must update your Dockerfiles to use dnf instead of yum when upgrading to the .NET 8 base image. For more information, see Introducing the Amazon Linux 2023 runtime for AWS Lambda.

Performance

There are a number of language performance improvements available as part of .NET 8. Initialization time can impact performance, as Lambda creates new execution environments to scale your function automatically. There are a number of ways to optimize performance for Lambda-based .NET workloads, including using source generators in System.Text.Json or using Native AOT.

Lambda has increased the default memory size from 256 MB to 512 MB in the blueprints and templates for improved performance with .NET 8. Perform your own functional and performance tests on your .NET 8 applications. You can use AWS Compute Optimizer or AWS Lambda Power Tuning for performance profiling.

At launch, new Lambda runtimes receive less usage than existing established runtimes. This can result in longer cold start times due to reduced cache residency within internal Lambda subsystems. Cold start times typically improve in the weeks following launch as usage increases. As a result, AWS recommends not drawing performance comparison conclusions with other Lambda runtimes until the performance has stabilized.

Native AOT

Lambda introduced .NET Native AOT support in November 2022. Benchmarks show up to 86% improvement in cold start times by eliminating the JIT compilation. Deploying .NET 8 Native AOT functions using the managed dotnet8 runtime rather than the OS-only provided.al2023 runtime gives your function access to .NET system libraries. For example, libicu, which is used for globalization, is not included by default in the provided.al2023 runtime but is in the dotnet8 runtime.

While Native AOT is not suitable for all .NET functions, .NET 8 has improved trimming support. This allows you to more easily run ASP.NET APIs. Improved trimming support helps eliminate build time trimming warnings, which highlight possible runtime errors. This can give you confidence that your Native AOT function behaves like a JIT-compiled function. Trimming support has been added to the Lambda runtime libraries, AWS .NET SDK, .NET Lambda Annotations, and .NET 8 itself.

Using.NET 8 with Lambda

To use .NET 8 with Lambda, you must update your tools.

  1. Install or update the .NET 8 SDK.
  2. If you are using AWS SAM, install or update to the latest version.
  3. If you are using Visual Studio, install or update the AWS Toolkit for Visual Studio.
  4. If you use the .NET Lambda Global Tools extension (Amazon.Lambda.Tools), install the CLI extension and templates. You can upgrade existing tools with dotnet tool update -g Amazon.Lambda.Tools and existing templates with dotnet new install Amazon.Lambda.Templates.

You can also use .NET 8 with Powertools for AWS Lambda (.NET), a developer toolkit to implement serverless best practices such as observability, batch processing, retrieving parameters, idempotency, and feature flags.

Building new .NET 8 functions

Using AWS SAM

  1. Run sam init.
  2. Choose 1- AWS Quick Start Templates.
  3. Choose one of the available templates such as Hello World Example.
  4. Select N for Use the most popular runtime and package type?
  5. Select dotnet8 as the runtime. The dotnet8 Hello World Example also includes a Native AOT template option.
  6. Follow the rest of the prompts to create the .NET 8 function.
AWS SAM .NET 8 init options

AWS SAM .NET 8 init options

You can amend the generated function code and use sam deploy --guided to deploy the function.

Using AWS Toolkit for Visual Studio

  1. From the Create a new project wizard, filter the templates to either the Lambda or Serverless project type and select a template. Use Lambda for deploying a single function. Use Serverless for deploying a collection of functions using AWS CloudFormation.
  2. Continue with the steps to finish creating your project.
  3. You can amend the generated function code.
  4. To deploy, right click on the project in the Solution Explorer and select Publish to AWS Lambda.

Using AWS extensions for the .NET CLI

  1. Run dotnet new list --tag Lambda to get a list of available Lambda templates.
  2. Choose a template and run dotnet new <template name>. To build a function using Native AOT, use dotnet new lambda.NativeAOT or dotnet new serverless.NativeAOT when using the .NET Lambda Annotations Framework.
  3. Locate the generated Lambda function in the directory under src which contains the .csproj file. You can amend the generated function code.
  4. To deploy, run dotnet lambda deploy-function and follow the prompts.
  5. You can test the function in the cloud using dotnet lambda invoke-function or by using the test functionality in the Lambda console.

You can build and deploy .NET Lambda functions using container images. Follow the instructions in the documentation.

Migrating from .NET 6 to .NET 8 without Native AOT

Using AWS SAM

  1. Open the template.yaml file.
  2. Update Runtime to dotnet8.
  3. Open a terminal window and rebuild the code using sam build.
  4. Run sam deploy to deploy the changes.

Using AWS Toolkit for Visual Studio

  1. Open the .csproj project file and update the TargetFramework to net8.0. Update NuGet packages for your Lambda functions to the latest version to pull in .NET 8 updates.
  2. Verify that the build command you are using is targeting the .NET 8 runtime.
  3. There may be additional steps depending on what build/deploy tool you’re using. Updating the function runtime may be sufficient.

.NET function in AWS Toolkit for Visual Studio

Using AWS extensions for the .NET CLI or AWS Toolkit for Visual Studio

  1. Open the aws-lambda-tools-defaults.json file if it exists.
    1. Set the framework field to net8.0. If unspecified, the value is inferred from the project file.
    2. Set the function-runtime field to dotnet8.
  2. Open the serverless.template file if it exists. For any AWS::Lambda::Function or AWS::Servereless::Function resources, set the Runtime property to dotnet8.
  3. Open the .csproj project file if it exists and update the TargetFramework to net8.0. Update NuGet packages for your Lambda functions to the latest version to pull in .NET 8 updates.

Migrating from .NET 6 to .NET 8 Native AOT

The following example migrates a .NET 6 class library function to a .NET 8 Native AOT executable function. This uses the optional Lambda Annotations framework which provides idiomatic .NET coding patterns.

Update your project file

  1. Open the project file.
  2. Set TargetFramework to net8.0.
  3. Set OutputType to exe.
  4. Remove PublishReadyToRun if it exists.
  5. Add PublishAot and set to true.
  6. Add or update NuGet package references to Amazon.Lambda.Annotations and Amazon.Lambda.RuntimeSupport. You can update using the NuGet UI in your IDE, manually, or by running dotnet add package Amazon.Lambda.RuntimeSupport and dotnet add package Amazon.Lambda.Annotations from your project directory.

Your project file should look similar to the following:

<Project Sdk="Microsoft.NET.Sdk">
  <PropertyGroup>
    <OutputType>exe</OutputType>
    <TargetFramework>net8.0</TargetFramework>
    <ImplicitUsings>enable</ImplicitUsings>
    <Nullable>enable</Nullable>
    <AWSProjectType>Lambda</AWSProjectType>
    <CopyLocalLockFileAssemblies>true</CopyLocalLockFileAssemblies>
    <!-- Generate native aot images during publishing to improve cold start time. -->
    <PublishAot>true</PublishAot>
	  <!-- StripSymbols tells the compiler to strip debugging symbols from the final executable if we're on Linux and put them into their own file. 
		This will greatly reduce the final executable's size.-->
	  <StripSymbols>true</StripSymbols>
  </PropertyGroup>
  <ItemGroup>
    <PackageReference Include="Amazon.Lambda.Core" Version="2.2.0" />
    <PackageReference Include="Amazon.Lambda.RuntimeSupport" Version="1.10.0" />
    <PackageReference Include="Amazon.Lambda.Serialization.SystemTextJson" Version="2.4.0" />
  </ItemGroup>
</Project>

Updating your function code

    1. Reference the annotations library with using Amazon.Lambda.Annotations;
    2. Add [assembly:LambdaGlobalProperties(GenerateMain = true)] to allow the annotations framework to create the main method. This is required as the project is now an executable instead of a library.
    3. Add the below partial class and include a JsonSerializable attribute for any types that you need to serialize, including for your function input and output This partial class is used at build time to generate reflection free code dedicated to serializing the listed types. The following is an example:
    4. /// <summary>
      /// This class is used to register the input event and return type for the FunctionHandler method with the System.Text.Json source generator.
      /// There must be a JsonSerializable attribute for each type used as the input and return type or a runtime error will occur 
      /// from the JSON serializer unable to find the serialization information for unknown types.
      /// </summary>
      [JsonSerializable(typeof(APIGatewayHttpApiV2ProxyRequest))]
      [JsonSerializable(typeof(APIGatewayHttpApiV2ProxyResponse))]
      public partial class MyCustomJsonSerializerContext : JsonSerializerContext
      {
          // By using this partial class derived from JsonSerializerContext, we can generate reflection free JSON Serializer code at compile time
          // which can deserialize our class and properties. However, we must attribute this class to tell it what types to generate serialization code for
          // See https://docs.microsoft.com/en-us/dotnet/standard/serialization/system-text-json-source-generation
      }

    5. After the using statement, add the following to specify the serializer to use. [assembly: LambdaSerializer(typeof(SourceGeneratorLambdaJsonSerializer<LambdaFunctionJsonSerializerContext>))]

    Swap LambdaFunctionJsonSerializerContext for your context if you are not using the partial class from the previous step.

    Updating your function configuration

    If you are using aws-lambda-tools-defaults.json.

    1. Set function-runtime to dotnet8.
    2. Set function-architecture to match your build machine – either x86_64 or arm64.
    3. Set (or update) environment-variables to include ANNOTATIONS_HANDLER=<YourFunctionHandler>. Replace <YourFunctionHandler> with the method name of your function handler, so the annotations framework knows which method to call from the generated main method.
    4. Set function-handler to the name of the executable assembly in your bin directory. By default, this is your project name, which tells the .NET Lambda bootstrap script to run your native binary instead of starting the .NET runtime. If your project file has AssemblyName then use that value for the function handler.
    {
      "function-architecture": "x86_64",
      "function-runtime": "dotnet8",
      "function-handler": "<your-assembly-name>",
      "environment-variables",
      "ANNOTATIONS_HANDLER=<your-function-handler>",
    }

    Deploy and test

    1. Deploy your function. If you are using Amazon.Lambda.Tools, run dotnet lambda deploy-function. Check for trim warnings during build and refactor to eliminate them.
    2. Test your function to ensure that the native calls into AL2023 are working correctly. By default, running local unit tests on your development machine won’t run natively and will still use the JIT compiler. Running with the JIT compiler does not allow you to catch native AOT specific runtime errors.

    Conclusion

    Lambda is introducing the new .NET 8 managed runtime. This post highlights new features in .NET 8. You can create new Lambda functions or migrate existing functions to .NET 8 or .NET 8 Native AOT.

    For more information, see the AWS Lambda for .NET repository, documentation, and .NET on Serverless Land.

    For more serverless learning resources, visit Serverless Land.

Re-platforming Java applications using the updated AWS Serverless Java Container

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/re-platforming-java-applications-using-the-updated-aws-serverless-java-container/

This post is written by Dennis Kieselhorst, Principal Solutions Architect.

The combination of portability, efficiency, community, and breadth of features has made Java a popular choice for businesses to build their applications for over 25 years. The introduction of serverless functions, pioneered by AWS Lambda, changed what you need in a programming language and runtime environment. Functions are often short-lived, single-purpose, and do not require extensive infrastructure configuration.

This blog post shows how you can modernize a legacy Java application to run on Lambda with minimal code changes using the updated AWS Serverless Java Container.

Deployment model comparison

Classic Java enterprise applications often run on application servers such as JBoss/ WildFly, Oracle WebLogic and IBM WebSphere, or servlet containers like Apache Tomcat. The underlying Java virtual machine typically runs 24/7 and serves multiple requests using its multithreading capabilities.

Typical long running Java application server

Typical long running Java application server

When building Lambda functions with Java, an HTTP server is no longer required and there are other considerations for running code in a Lambda environment. Code runs in an execution environment, which processes a single invocation at a time. Functions can run for up to 15 minutes with a maximum of 10 Gb allocated memory.

Functions are triggered by events such as an HTTP request with a corresponding payload. An Amazon API Gateway HTTP request invokes the function with the following JSON payload:

Amazon API Gateway HTTP request payload

Amazon API Gateway HTTP request payload

The code to process these events is different from how you implement it in a traditional application.

AWS Serverless Java Container

The AWS Serverless Java Container makes it easier to run Java applications written with frameworks such as Spring, Spring Boot, or JAX-RS/Jersey in Lambda.

The container provides adapter logic to minimize code changes. Incoming events are translated to the Servlet specification so that frameworks work as before.

AWS Serverless Java Container adapter

AWS Serverless Java Container adapter

Version 1 of this library was released in 2018. Today, AWS is announcing the release of version 2, which supports the latest Jakarta EE specification, along with Spring Framework 6.x, Spring Boot 3.x and Jersey 3.x.

Example: Modifying a Spring Boot application

This following example illustrates how to migrate a Spring Boot 3 application. You can find the full example for Spring and other frameworks in the GitHub repository.

  1. Add the AWS Serverless Java dependency to your Maven POM build file (or Gradle accordingly):
  2. <dependency>
        <groupId>com.amazonaws.serverless</groupId>
        <artifactId>aws-serverless-java-container-springboot3</artifactId>
        <version>2.0.0</version>
    </dependency>
  3. Spring Boot, by default, embeds Apache Tomcat to deal with HTTP requests. The examples use Amazon API Gateway to handle inbound HTTP requests so you can exclude the dependency.
  4. <build>
        <plugins>
            <plugin>
                <groupId>org.apache.maven.plugins</groupId>
                <artifactId>maven-shade-plugin</artifactId>
                <configuration>
                    <createDependencyReducedPom>false</createDependencyReducedPom>
                </configuration>
                <executions>
                    <execution>
                        <phase>package</phase>
                        <goals>
                            <goal>shade</goal>
                        </goals>
                        <configuration>
                            <artifactSet>
                                <excludes>
                                    <exclude>org.apache.tomcat.embed:*</exclude>
                                </excludes>
                            </artifactSet>
                        </configuration>
                    </execution>
                </executions>
            </plugin>
        </plugins>
    </build>

    The AWS Serverless Java Container accepts API Gateway proxy requests and transforms them into a plain Java object. The library also transforms outputs into a suitable API Gateway response object.

    Once you run your build process, Maven’s Shade-plugin now produces an Uber-JAR that bundles all dependencies, which you can upload to Lambda.

  5. The Lambda runtime must know which handler method to invoke. You can configure and use the SpringDelegatingLambdaContainerHandler implementation or implement your own handler Java class that delegates to AWS Serverless Java Container. This is useful if you want to add additional functionality.
  6. Configure the handler name in the runtime settings of your function.
  7. Configure the handler name

    Configure the handler name

  8. Configure an environment variable named MAIN_CLASS to let the generic handler know where to find your original application main class, which is usually annotated with @SpringBootApplication.
  9. Configure MAIN_CLASS environment variable

    Configure MAIN_CLASS environment variable

    You can also configure these settings using infrastructure as code (IaC) tools such as AWS CloudFormation, the AWS Cloud Development Kit (AWS CDK), or the AWS Serverless Application Model (AWS SAM).

    In an AWS SAM template, the related changes are as follows. Full templates are part of the GitHub repository.

    Handler: com.amazonaws.serverless.proxy.spring.SpringDelegatingLambdaContainerHandler 
    Environment:
      Variables:
        MAIN_CLASS: com.amazonaws.serverless.sample.springboot3.Application

    Optimizing memory configuration

    When running Lambda functions, start-up time and memory footprint are important considerations. The amount of memory you configure for your Lambda function also determines the amount of virtual CPU available. Adding more memory proportionally increases the amount of CPU, and therefore increases the overall computational power available. If a function is CPU-, network- or memory-bound, adding more memory can improve performance.

    Lambda charges for the total amount of gigabyte-seconds consumed by a function. Gigabyte-seconds are a combination of total memory (in gigabytes) and duration (in seconds). Increasing memory incurs additional cost. However, in many cases, increasing the memory available causes a decrease in the function duration due to the additional CPU available. As a result, the overall cost increase may be negligible for additional performance, or may even decrease.

    Choosing the memory allocated to your Lambda functions is an optimization process that balances speed (duration) and cost. You can manually test functions by selecting different memory allocations and measuring the completion time. AWS Lambda Power Tuning is a tool to simplify and automate the process, which you can use to optimize your configuration.

    Power Tuning uses AWS Step Functions to run multiple concurrent versions of a Lambda function at different memory allocations and measures the performance. The function runs in your AWS account, performing live HTTP calls and SDK interactions, to measure performance in a production scenario.

    Improving cold-start time with AWS Lambda SnapStart

    Traditional applications often have a large tree of dependencies. Lambda loads the function code and initializes dependencies during Lambda lifecycle initialization phase. With many dependencies, this initialization time may be too long for your requirements. AWS Lambda SnapStart for Java based functions can deliver up to 10 times faster startup performance.

    Instead of running the function initialization phase on every cold-start, Lambda SnapStart runs the function initialization process at deployment time. Lambda takes a snapshot of the initialized execution environment. This snapshot is encrypted and persisted in a tiered cache for low latency access. When the function is invoked and scales, Lambda resumes the execution environment from the persisted snapshot instead of running the full initialization process. This results in lower startup latency.

    To enable Lambda SnapStart you must first enable the configuration setting, and also publish a function version.

    Enabling SnapStart

    Enabling SnapStart

    Ensure you point your API Gateway endpoint to the published version or an alias to ensure you are using the SnapStart enabled function.

    The corresponding settings in an AWS SAM template contain the following:

    SnapStart: 
      ApplyOn: PublishedVersions
    AutoPublishAlias: my-function-alias

    Read the Lambda SnapStart compatibility considerations in the documentation as your application may contain specific code that requires attention.

    Conclusion

    When building serverless applications with Lambda, you can deliver features faster, but your language and runtime must work within the serverless architectural model. AWS Serverless Java Container helps to bridge between traditional Java Enterprise applications and modern cloud-native serverless functions.

    You can optimize the memory configuration of your Java Lambda function using AWS Lambda Power Tuning tool and enable SnapStart to optimize the initial cold-start time.

    The self-paced Java on AWS Lambda workshop shows how to build cloud-native Java applications and migrate existing Java application to Lambda.

    Explore the AWS Serverless Java Container GitHub repo where you can report related issues and feature requests.

    For more serverless learning resources, visit Serverless Land.

Build real-time applications with Amazon EventBridge and AWS AppSync

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/build-real-time-applications-with-amazon-eventbridge-and-aws-appsync/

This post is written by Josh Kahn, Tech Leader, Serverless.

Amazon EventBridge now supports publishing events to AWS AppSync GraphQL APIs as native targets. The new integration enables builders to publish events easily to a wider variety of consumers and simplifies updating clients with near real-time data. You can use EventBridge and AWS AppSync to build resilient, subscription-based event-driven architectures across consumers.

To illustrate using EventBridge with AWS AppSync, consider a simplified airport operations scenario. In this example, airlines publish flight events (for example, boarding, push back, gate changes, and delays) to a service that maintains flight status on in-airport displays. Airlines also publish events that are useful for other entities at the airport, such as baggage handlers and maintenance, but not to passengers. This depicts a conceptual view of the system:

Conceptual view of the system

Passengers want the in-airport displays to be up-to-date and accurate. There are a number of ways to design the display application so that data remains up-to-date. Broadly, these include the application polling some API or the application subscribing to data changes.

Subscriptions for this scenario are better as the data changes are small and incremental relative to the large amount of information displayed. In a delay, for example, the display updates the status and departure time but no other details of a single flight among a larger list of flight information.

Flight board

AWS AppSync can enable clients to listen for real-time data changes through the use of GraphQL subscriptions. These are implemented using a WebSocket connection between the client and the AWS AppSync service. The display application client invokes the GraphQL subscription operation to establish a secure connection. AWS AppSync will automatically push data changes (or mutations) via the GraphQL API to subscribers using that connection.

Previously, builders could use EventBridge API Destinations to wire events published and routed through EventBridge to AWS AppSync, as described in an earlier blog post, and available in Serverless Land patterns (API Key, OAuth). The approach is useful for dealing with “out-of-band” updates in which data changes outside of an AWS AppSync mutation. Out-of-band updates generally require a NONE data source in AWS AppSync to notify subscribers of changes, as described in the AWS re:Post Knowledge Center. The addition of AWS AppSync as a target for EventBridge simplifies these use cases as you can now trigger a mutation in response to an event without additional code.

Airport Operations Events

Expanding the scenario, airport operations events look like this:

{
  "flightNum": 123,
  "carrierCode": "JK",
  "date": "2024-01-25",
  "event": "FlightDelayed",
  "message": "Delayed 15 minutes, late aircraft",
  "info": "{ \"newDepTime\": \"2024-01-25T13:15:00Z\", \"delayMinutes\": 15 }"
}

The event field identifies the type of event and if it is relevant to passengers. The event details provide further information about the event, which varies based on the type of event. The airport publishes a variety of events but the airport displays only need a subset of those changes.

AWS AppSync GraphQL APIs start with a GraphQL schema that defines the types, fields, and operations available in that API. AWS AppSync documentation provides an overview of schema and other GraphQL essentials. The partial GraphQL schema for the airport scenario is as follows:


type DelayEventInfo implements EventInfo {
	message: String
	delayMinutes: Int
	newDepTime: AWSDateTime
}

interface EventInfo {
	message: String
}

enum StatusEvent {
	FlightArrived
	FlightBoarding
	FlightCancelled
	FlightDelayed
	FlightGateChanged
	FlightLanded
	FlightPushBack
	FlightTookOff
}

type StatusUpdate {
	num: Int!
	carrier: String!
	date: AWSDate!
	event: StatusEvent!
	info: EventInfo
}

input StatusUpdateInput {
	num: Int!
	carrier: String!
	date: AWSDate!
	event: StatusEvent!
	message: String
	extra: AWSJSON
}

type Mutation {
	updateFlightStatus(input: StatusUpdateInput!): StatusUpdate!
}

type Query {
	listStatusUpdates(by: String): [StatusUpdate]
}

type Subscription {
	onFlightStatusUpdate(date: AWSDate, carrier: String): StatusUpdate
		@aws_subscribe(mutations: ["updateFlightStatus"])
}

schema {
	query: Query
	mutation: Mutation
	subscription: Subscription
}

Connect EventBridge to AWS AppSync

EventBridge allows you to filter, transform, and route events to a number of targets. The airport display service only needs events that directly impact passengers. You can define a rule in EventBridge that routes only those events (included in the preceding GraphQL schema) to the AWS AppSync target. Other events are routed elsewhere, as defined by other rules, or dropped. Details on creating EventBridge rules and the event matching pattern format can be found in EventBridge documentation.

The previous flight delayed event would be delivered using EventBridge as follows:

{
  "id": "b051312994104931b0980d1ad1c5340f",
  "detail-type": "Operations: Flight delayed",
  "source": "airport-operations",
  "time": "2024-01-25T16:58:37Z",
  "detail": {
    "flightNum": 123,
    "carrierCode": "JK",
    "date": "2024-01-25",
    "event": "FlightDelayed",
    "message": "Delayed 15 minutes, late aircraft",
    "info": "{ \"newDepTime\": \"2024-01-25T13:15:00Z\", \"delayMinutes\": 15 }"
  }
}

In this scenario, there is a specific list of events of interest, but EventBridge provides a flexible set of operations to match patterns, inspect arrays, and filter by content using prefix, numerical, or other matching. Some organizations will also allow subscribers to define their own rules on an EventBridge event bus, allowing targets to subscribe to events via self-service.

The following event pattern matches on the events needed for the airport display service:

{
  "source": [ "airport-operations" ],
  "detail": {
    "event": [ "FlightArrived", "FlightBoarding", "FlightCancelled", ... ]
  }
}

To create a new EventBridge rule, you can use the AWS Management Console or infrastructure as code. You can find the CloudFormation definition for the completed rule, with the AWS AppSync target, later in this post.

Console view

Create the AWS AppSync target

Now that EventBridge is configured to route selected events, define AWS AppSync as the target for the rule. The AWS AppSync API must support IAM authorization to be used as an EventBridge target. AWS AppSync supports multiple authorization types on a single GraphQL type, so you can also use OpenID Connect, Amazon Cognito User Pools, or other authorization methods as needed.

To configure AWS AppSync as an EventBridge target, define the target using the AWS Management Console or infrastructure as code. In the console, select the Target Type as “AWS Service” and Target as “AppSync.” Select your API. EventBridge parses the GraphQL schema and allows you to select the mutation to invoke when the rule is triggered.

When using the AWS Management Console, EventBridge will also configure the necessary AWS IAM role to invoke the selected mutation. Remember to create and associate a role with an appropriate trust policy when configuring with IaC.

EventBridge target types

EventBridge supports input transformation to customize the contents of an event before passing the information as input to the target. Configure the input transformer to extract needed values from the event using JSON path and a template in the input format expected by the AWS AppSync API. EventBridge provides a handy utility in the Console to pass and test the output of a sample event.

Target input transformer

Finally, configure the selection set to include the response from the AWS AppSync API. These are the fields that will be returned to EventBridge when the mutation is invoked. While the result returned to EventBridge is not overly useful (aside from troubleshooting), the mutation selection set will also determine the fields available to subscribers to the onFlightStatusUpdate subscription.

Configuring the selection set

Define the EventBridge to AWS AppSync rule in CloudFormation

Infrastructure as code templates, including AWS CloudFormation and AWS CDK, are useful for codifying infrastructure definitions to deploy across Regions and accounts. While you can write CloudFormation by hand, EventBridge provides a useful CloudFormation export in the AWS Management Console. You can use this feature to export the definition for a defined rule.

Export definition

This is the CloudFormation for the previous configured rule and AWS AppSync target. This snippet includes both the rule definition and the target configuration.

PassengerEventsToDisplayServiceRule:
    Type: AWS::Events::Rule
    Properties:
      Description: Route passenger related events to the display service endpoint
      EventBusName: eb-to-appsync
      EventPattern:
        source:
          - airport-operations
        detail:
          event:
            - FlightArrived
            - FlightBoarding
            - FlightCancelled
            - FlightDelayed
            - FlightGateChanged
            - FlightLanded
            - FlightPushBack
            - FlightTookOff
      Name: passenger-events-to-display-service
      State: ENABLED
      Targets:
        - Id: 12344535353263463
          Arn: <AppSync API GraphQL API ARN>
          RoleArn: <EventBridge Role ARN (defined elsewhere)>
          InputTransformer:
            InputPathsMap:
              carrier: $.detail.carrierCode
              date: $.detail.date
              event: $.detail.event
              extra: $.detail.info
              message: $.detail.message
              num: $.detail.flightNum
            InputTemplate: |-
              {
                "input": {
                  "num": <num>,
                  "carrier": <carrier>,
                  "date": <date>,
                  "event": <event>,
                  "message": "<message>",
                  "extra": <extra>
                }
              }
          AppSyncParameters:
            GraphQLOperation: >-
              mutation
              UpdateFlightStatus($input:StatusUpdateInput!){updateFlightStatus(input:$input){
                event
                date
                carrier
                num
                info {
                  __typename
                  ... on DelayEventInfo {
                    message
                    delayMinutes
                    newDepTime
                  }
                }
              }}

The ARN of the AWS AppSync API follows the form arn:aws:appsync:<AWS_REGION>:<ACCOUNT_ID>:endpoints/graphql-api/<GRAPHQL_ENDPOINT_ID>. The ARN is available in CloudFormation (see GraphQLEndpointArn return value) or can be created using the identifier found in the AWS AppSync GraphQL endpoint. The ARN included in the EventBridge execution role policy is the AWS AppSync API ARN (a different ARN).

The AppSyncParameters field includes the GraphQL operation for EventBridge to invoke on the AWS AppSync API. This must be well formatted and match the GraphQL schema. Include any fields that must be available to subscribers in the selection set.

Testing subscriptions

AWS AppSync is now configured as a target for the EventBridge rule. The real-life display application would use a GraphQL library, such as AWS Amplify, to subscribe to real-time data changes. The AWS Management Console provides a useful utility to test. Navigate to the AWS AppSync console and select Queries in the menu for your API. Enter the following query and choose Run to subscribe for data changes:

subscription MySubscription {
  onFlightStatusUpdate {
    carrier
    date
    event
    num
    info {
      __typename
      … on DelayEventInfo {
        message
        delayMinutes
        newDepTime
      }
    }
  }
}

In a separate browser tab, navigate to the EventBridge console, and choose Send events. On the Send events page, select the required event bus and set the Event source to “airport-operations.” Then enter a detail type of your choice. Finally, paste the following as the Event detail, then choose Send.

{
  "id": "b051312994104931b0980d1ad1c5340f",
  "detail-type": "Operations: Flight delayed",
  "source": "airport-operations",
  "time": "2024-01-25T16:58:37Z",
  "detail": {
    "flightNum": 123,
    "carrierCode": "JK",
    "date": "2024-01-25",
    "event": "FlightDelayed",
    "message": "Delayed 15 minutes, late aircraft",
    "info": "{ \"newDepTime\": \"2024-01-25T13:15:00Z\", \"delayMinutes\": 15 }"
  }
}

Return to the AWS AppSync tab in your browser to see the changed data in the result pane:

Result pane

Conclusion

Directly invoking AWS AppSync GraphQL API targets from EventBridge simplifies and streamlines integration between these two services, ideal for notifying a variety of subscribers of data changes in event-driven workloads. You can also take advantage of other features available from the two services. For example, use AWS AppSync enhanced subscription filtering to update only airport displays in the terminal in which they are located.

To learn more about serverless, visit Serverless Land for a wide array of reusable patterns, tutorials, and learning materials. Newly added to the pattern library is an EventBridge to AWS AppSync pattern similar to the one described in this post. Visit EventBridge documentation for more details.

For more serverless learning resources, visit Serverless Land.

Invoking on-premises resources interactively using AWS Step Functions and MQTT

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/invoking-on-premises-resources-interactively-using-aws-step-functions-and-mqtt/

This post is written by Alex Paramonov, Sr. Solutions Architect, ISV, and Pieter Prinsloo, Customer Solutions Manager.

Workloads in AWS sometimes require access to data stored in on-premises databases and storage locations. Traditional solutions to establish connectivity to the on-premises resources require inbound rules to firewalls, a VPN tunnel, or public endpoints.

This blog post demonstrates how to use the MQTT protocol (AWS IoT Core) with AWS Step Functions to dispatch jobs to on-premises workers to access or retrieve data stored on-premises. The state machine can communicate with the on-premises workers without opening inbound ports or the need for public endpoints on on-premises resources. Workers can run behind Network Access Translation (NAT) routers while keeping bidirectional connectivity with the AWS Cloud. This provides a more secure and cost-effective way to access data stored on-premises.

Overview

By using Step Functions with AWS Lambda and AWS IoT Core, you can access data stored on-premises securely without altering the existing network configuration.

AWS IoT Core lets you connect IoT devices and route messages to AWS services without managing infrastructure. By using a Docker container image running on-premises as a proxy IoT Thing, you can take advantage of AWS IoT Core’s fully managed MQTT message broker for non-IoT use cases.

MQTT subscribers receive information via MQTT topics. An MQTT topic acts as a matching mechanism between publishers and subscribers. Conceptually, an MQTT topic behaves like an ephemeral notification channel. You can create topics at scale with virtually no limit to the number of topics. In SaaS applications, for example, you can create topics per tenant. Learn more about MQTT topic design here.

The following reference architecture shown uses the AWS Serverless Application Model (AWS SAM) for deployment, Step Functions to orchestrate the workflow, AWS Lambda to send and receive on-premises messages, and AWS IoT Core to provide the MQTT message broker, certificate and policy management, and publish/subscribe topics.

Reference architecture

  1. Start the state machine, either “on demand” or on a schedule.
  2. The state: “Lambda: Invoke Dispatch Job to On-Premises” publishes a message to an MQTT message broker in AWS IoT Core.
  3. The message broker sends the message to the topic corresponding to the worker (tenant) in the on-premises container that runs the job.
  4. The on-premises container receives the message and starts work execution. Authentication is done using client certificates and the attached policy limits the worker access to only the tenant’s topic.
  5. The worker in the on-premises container can access local resources like DBs or storage locations.
  6. The on-premises container sends the results and job status back to another MQTT topic.
  7. The AWS IoT Core rule invokes the “TaskToken Done” Lambda function.
  8. The Lambda function submits the results to Step Functions via SendTaskSuccess or SendTaskFailure API.

Deploying and testing the sample

Ensure you can manage AWS resources from your terminal and that:

  • Latest versions of AWS CLI and AWS SAM CLI are installed.
  • You have an AWS account. If not, visit this page.
  • Your user has sufficient permissions to manage AWS resources.
  • Git is installed.
  • Python version 3.11 or greater is installed.
  • Docker is installed.

You can access the GitHub repository here and follow these steps to deploy the sample.

The aws-resources directory contains the required AWS resources including the state machine, Lambda functions, topics, and policies. The directory on-prem-worker contains the Docker container image artifacts. Use it to run the on-premises worker locally.

In this example, the worker container adds two numbers, provided as an input in the following format:

{
  "a": 15,
  "b": 42
}

In a real-world scenario, you can substitute this operation with business logic. For example, retrieving data from on-premises databases, generating aggregates, and then submitting the results back to your state machine.

Follow these steps to test the sample end-to-end.

Using AWS IoT Core without IoT devices

There are no IoT devices in the example use case. However, the fully managed MQTT message broker in AWS IoT Core lets you route messages to AWS services without managing infrastructure.

AWS IoT Core authenticates clients using X.509 client certificates. You can attach a policy to a client certificate allowing the client to publish and subscribe only to certain topics. This approach does not require IAM credentials inside the worker container on-premises.

AWS IoT Core’s security, cost efficiency, managed infrastructure, and scalability make it a good fit for many hybrid applications beyond typical IoT use cases.

Dispatching jobs from Step Functions and waiting for a response

When a state machine reaches the state to dispatch the job to an on-premises worker, the execution pauses and waits until the job finishes. Step Functions support three integration patterns: Request-Response, Sync Run a Job, and Wait for a Callback with Task Token. The sample uses the “Wait for a Callback with Task Token“ integration. It allows the state machine to pause and wait for a callback for up to 1 year.

When the on-premises worker completes the job, it publishes a message to the topic in AWS IoT Core. A rule in AWS IoT Core then invokes a Lambda function, which sends the result back to the state machine by calling either SendTaskSuccess or SendTaskFailure API in Step Functions.

You can prevent the state machine from timing out by adding HeartbeatSeconds to the task in the Amazon States Language (ASL). Timeouts happen if the job freezes and the SendTaskFailure API is not called. HeartbeatSeconds send heartbeats from the worker via the SendTaskHeartbeat API call and should be less than the specified TimeoutSeconds.

To create a task in ASL for your state machine, which waits for a callback token, use the following code:

{
      "Type": "Task",
      "Resource": "arn:aws:states:::lambda:invoke.waitForTaskToken",
      "Parameters": {
        "FunctionName": "${LambdaNotifierToWorkerArn}",
        "Payload": {
          "Input.$": "$",
          "TaskToken.$": "$$.Task.Token"
        }
}

The .waitForTaskToken suffix indicates that the task must wait for the callback. The state machine generates a unique callback token, accessible via the $$.Task.Token built-in variable, and passes it as an input to the Lambda function defined in FunctionName.

The Lambda function then sends the token to the on-premises worker via an AWS IoT Core topic.

Lambda is not the only service that supports Wait for Callback integration – see the full list of supported services here.

In addition to dispatching tasks and getting the result back, you can implement progress tracking and shut down mechanisms. To track progress, the worker sends metrics via a separate topic.

Depending on your current implementation, you have several options:

  1. Storing progress data from the worker in Amazon DynamoDB and visualizing it via REST API calls to a Lambda function, which reads from the DynamoDB table. Refer to this tutorial on how to store data in DynamoDB directly from the topic.
  2. For a reactive user experience, create a rule to invoke a Lambda function when new progress data arrives. Open a WebSocket connection to your backend. The Lambda function sends progress data via WebSocket directly to the frontend.

To implement a shutdown mechanism, you can run jobs in separate threads on your worker and subscribe to the topic, to which your state machine publishes the shutdown messages. If a shutdown message arrives, end the job thread on the worker and send back the status including the callback token of the task.

Using AWS IoT Core Rules and Lambda Functions

A message with job results from the worker does not arrive to the Step Functions API directly. Instead, an AWS IoT Core Rule and a dedicated Lambda function forward the status message to Step Functions. This allows for more granular permissions in AWS IoT Core policies, which result in improved security because the worker container can only publish and subscribe to specific topics. No IAM credentials exist on-premises.

The Lambda function’s execution role contains the permissions for SendTaskSuccess, SendTaskHeartbeat, and SendTaskFailure API calls only.

Alternatively, a worker can run API calls in Step Functions workflows directly, which replaces the need for a topic in AWS IoT Core, a rule, and a Lambda function to invoke the Step Functions API. This approach requires IAM credentials inside the worker’s container. You can use AWS Identity and Access Management Roles Anywhere to obtain temporary security credentials. As your worker’s functionality evolves over time, you can add further AWS API calls while adding permissions to the IAM execution role.

Cleaning up

The services used in this solution are eligible for AWS Free Tier. To clean up the resources in the aws-resources/ directory of the repository run:

sam delete

This removes all resources provisioned by the template.yml file.

To remove the client certificate from AWS, navigate to AWS IoT Core Certificates and delete the certificate, which you added during the manual deployment steps.

Lastly, stop the Docker container on-premises and remove it:

docker rm --force mqtt-local-client

Finally, remove the container image:

docker rmi mqtt-client-waitfortoken

Conclusion

Accessing on-premises resources with workers controlled via Step Functions using MQTT and AWS IoT Core is a secure, reactive, and cost effective way to run on-premises jobs. Consider updating your hybrid workloads from using inefficient polling or schedulers to the reactive approach described in this post. This offers an improved user experience with fast dispatching and tracking of jobs outside of cloud.

For more serverless learning resources, visit Serverless Land.

Use Amazon Athena with Spark SQL for your open-source transactional table formats

Post Syndicated from Pathik Shah original https://aws.amazon.com/blogs/big-data/use-amazon-athena-with-spark-sql-for-your-open-source-transactional-table-formats/

AWS-powered data lakes, supported by the unmatched availability of Amazon Simple Storage Service (Amazon S3), can handle the scale, agility, and flexibility required to combine different data and analytics approaches. As data lakes have grown in size and matured in usage, a significant amount of effort can be spent keeping the data consistent with business events. To ensure files are updated in a transactionally consistent manner, a growing number of customers are using open-source transactional table formats such as Apache Iceberg, Apache Hudi, and Linux Foundation Delta Lake that help you store data with high compression rates, natively interface with your applications and frameworks, and simplify incremental data processing in data lakes built on Amazon S3. These formats enable ACID (atomicity, consistency, isolation, durability) transactions, upserts, and deletes, and advanced features such as time travel and snapshots that were previously only available in data warehouses. Each storage format implements this functionality in slightly different ways; for a comparison, refer to Choosing an open table format for your transactional data lake on AWS.

In 2023, AWS announced general availability for Apache Iceberg, Apache Hudi, and Linux Foundation Delta Lake in Amazon Athena for Apache Spark, which removes the need to install a separate connector or associated dependencies and manage versions, and simplifies the configuration steps required to use these frameworks.

In this post, we show you how to use Spark SQL in Amazon Athena notebooks and work with Iceberg, Hudi, and Delta Lake table formats. We demonstrate common operations such as creating databases and tables, inserting data into the tables, querying data, and looking at snapshots of the tables in Amazon S3 using Spark SQL in Athena.

Prerequisites

Complete the following prerequisites:

Download and import example notebooks from Amazon S3

To follow along, download the notebooks discussed in this post from the following locations:

After you download the notebooks, import them into your Athena Spark environment by following the To import a notebook section in Managing notebook files.

Navigate to specific Open Table Format section

If you are interested in Iceberg table format, navigate to Working with Apache Iceberg tables section.

If you are interested in Hudi table format, navigate to Working with Apache Hudi tables section.

If you are interested in Delta Lake table format, navigate to Working with Linux foundation Delta Lake tables section.

Working with Apache Iceberg tables

When using Spark notebooks in Athena, you can run SQL queries directly without having to use PySpark. We do this by using cell magics, which are special headers in a notebook cell that change the cell’s behavior. For SQL, we can add the %%sql magic, which will interpret the entire cell contents as a SQL statement to be run on Athena.

In this section, we show how you can use SQL on Apache Spark for Athena to create, analyze, and manage Apache Iceberg tables.

Set up a notebook session

In order to use Apache Iceberg in Athena, while creating or editing a session, select the Apache Iceberg option by expanding the Apache Spark properties section. It will pre-populate the properties as shown in the following screenshot.

This image shows the Apache Iceberg properties set while creating Spak session in Athena.

For steps, see Editing session details or Creating your own notebook.

The code used in this section is available in the SparkSQL_iceberg.ipynb file to follow along.

Create a database and Iceberg table

First, we create a database in the AWS Glue Data Catalog. With the following SQL, we can create a database called icebergdb:

%%sql
CREATE DATABASE icebergdb

Next, in the database icebergdb, we create an Iceberg table called noaa_iceberg pointing to a location in Amazon S3 where we will load the data. Run the following statement and replace the location s3://<your-S3-bucket>/<prefix>/ with your S3 bucket and prefix:

%%sql
CREATE TABLE icebergdb.noaa_iceberg(
station string,
date string,
latitude string,
longitude string,
elevation string,
name string,
temp string,
temp_attributes string,
dewp string,
dewp_attributes string,
slp string,
slp_attributes string,
stp string,
stp_attributes string,
visib string,
visib_attributes string,
wdsp string,
wdsp_attributes string,
mxspd string,
gust string,
max string,
max_attributes string,
min string,
min_attributes string,
prcp string,
prcp_attributes string,
sndp string,
frshtt string)
USING iceberg
PARTITIONED BY (year string)
LOCATION 's3://<your-S3-bucket>/<prefix>/noaaiceberg/'

Insert data into the table

To populate the noaa_iceberg Iceberg table, we insert data from the Parquet table sparkblogdb.noaa_pq that was created as part of the prerequisites. You can do this using an INSERT INTO statement in Spark:

%%sql
INSERT INTO icebergdb.noaa_iceberg select * from sparkblogdb.noaa_pq

Alternatively, you can use CREATE TABLE AS SELECT with the USING iceberg clause to create an Iceberg table and insert data from a source table in one step:

%%sql
CREATE TABLE icebergdb.noaa_iceberg
USING iceberg
PARTITIONED BY (year)
AS SELECT * FROM sparkblogdb.noaa_pq

Query the Iceberg table

Now that the data is inserted in the Iceberg table, we can start analyzing it. Let’s run a Spark SQL to find the minimum recorded temperature by year for the 'SEATTLE TACOMA AIRPORT, WA US' location:

%%sql
select name, year, min(MIN) as minimum_temperature
from icebergdb.noaa_iceberg
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

We get following output.

Image shows output of first select query

Update data in the Iceberg table

Let’s look at how to update data in our table. We want to update the station name 'SEATTLE TACOMA AIRPORT, WA US' to 'Sea-Tac'. Using Spark SQL, we can run an UPDATE statement against the Iceberg table:

%%sql
UPDATE icebergdb.noaa_iceberg
SET name = 'Sea-Tac'
WHERE name = 'SEATTLE TACOMA AIRPORT, WA US'

We can then run the previous SELECT query to find the minimum recorded temperature for the 'Sea-Tac' location:

%%sql
select name, year, min(MIN) as minimum_temperature
from icebergdb.noaa_iceberg
where name = 'Sea-Tac'
group by 1,2

We get the following output.

Image shows output of second select query

Compact data files

Open table formats like Iceberg work by creating delta changes in file storage, and tracking the versions of rows through manifest files. More data files leads to more metadata stored in manifest files, and small data files often cause an unnecessary amount of metadata, resulting in less efficient queries and higher Amazon S3 access costs. Running Iceberg’s rewrite_data_files procedure in Spark for Athena will compact data files, combining many small delta change files into a smaller set of read-optimized Parquet files. Compacting files speeds up the read operation when queried. To run compaction on our table, run the following Spark SQL:

%%sql
CALL spark_catalog.system.rewrite_data_files
(table => 'icebergdb.noaa_iceberg', strategy=>'sort', sort_order => 'zorder(name)')

rewrite_data_files offers options to specify your sort strategy, which can help reorganize and compact data.

List table snapshots

Each write, update, delete, upsert, and compaction operation on an Iceberg table creates a new snapshot of a table while keeping the old data and metadata around for snapshot isolation and time travel. To list the snapshots of an Iceberg table, run the following Spark SQL statement:

%%sql
SELECT *
FROM spark_catalog.icebergdb.noaa_iceberg.snapshots

Expire old snapshots

Regularly expiring snapshots is recommended to delete data files that are no longer needed, and to keep the size of table metadata small. It will never remove files that are still required by a non-expired snapshot. In Spark for Athena, run the following SQL to expire snapshots for the table icebergdb.noaa_iceberg that are older than a specific timestamp:

%%sql
CALL spark_catalog.system.expire_snapshots
('icebergdb.noaa_iceberg', TIMESTAMP '2023-11-30 00:00:00.000')

Note that the timestamp value is specified as a string in format yyyy-MM-dd HH:mm:ss.fff. The output will give a count of the number of data and metadata files deleted.

Drop the table and database

You can run the following Spark SQL to clean up the Iceberg tables and associated data in Amazon S3 from this exercise:

%%sql
DROP TABLE icebergdb.noaa_iceberg PURGE

Run the following Spark SQL to remove the database icebergdb:

%%sql
DROP DATABASE icebergdb

To learn more about all the operations you can perform on Iceberg tables using Spark for Athena, refer to Spark Queries and Spark Procedures in the Iceberg documentation.

Working with Apache Hudi tables

Next, we show how you can use SQL on Spark for Athena to create, analyze, and manage Apache Hudi tables.

Set up a notebook session

In order to use Apache Hudi in Athena, while creating or editing a session, select the Apache Hudi option by expanding the Apache Spark properties section.

This image shows the Apache Hudi properties set while creating Spak session in Athena.

For steps, see Editing session details or Creating your own notebook.

The code used in this section should be available in the SparkSQL_hudi.ipynb file to follow along.

Create a database and Hudi table

First, we create a database called hudidb that will be stored in the AWS Glue Data Catalog followed by Hudi table creation:

%%sql
CREATE DATABASE hudidb

We create a Hudi table pointing to a location in Amazon S3 where we will load the data. Note that the table is of copy-on-write type. It is defined by type= 'cow' in the table DDL. We have defined station and date as the multiple primary keys and preCombinedField as year. Also, the table is partitioned on year. Run the following statement and replace the location s3://<your-S3-bucket>/<prefix>/ with your S3 bucket and prefix:

%%sql
CREATE TABLE hudidb.noaa_hudi(
station string,
date string,
latitude string,
longitude string,
elevation string,
name string,
temp string,
temp_attributes string,
dewp string,
dewp_attributes string,
slp string,
slp_attributes string,
stp string,
stp_attributes string,
visib string,
visib_attributes string,
wdsp string,
wdsp_attributes string,
mxspd string,
gust string,
max string,
max_attributes string,
min string,
min_attributes string,
prcp string,
prcp_attributes string,
sndp string,
frshtt string,
year string)
USING HUDI
PARTITIONED BY (year)
TBLPROPERTIES(
primaryKey = 'station, date',
preCombineField = 'year',
type = 'cow'
)
LOCATION 's3://<your-S3-bucket>/<prefix>/noaahudi/'

Insert data into the table

Like with Iceberg, we use the INSERT INTO statement to populate the table by reading data from the sparkblogdb.noaa_pq table created in the previous post:

%%sql
INSERT INTO hudidb.noaa_hudi select * from sparkblogdb.noaa_pq

Query the Hudi table

Now that the table is created, let’s run a query to find the maximum recorded temperature for the 'SEATTLE TACOMA AIRPORT, WA US' location:

%%sql
select name, year, max(MAX) as maximum_temperature
from hudidb.noaa_hudi
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

Update data in the Hudi table

Let’s change the station name 'SEATTLE TACOMA AIRPORT, WA US' to 'Sea–Tac'. We can run an UPDATE statement on Spark for Athena to update the records of the noaa_hudi table:

%%sql
UPDATE hudidb.noaa_hudi
SET name = 'Sea-Tac'
WHERE name = 'SEATTLE TACOMA AIRPORT, WA US'

We run the previous SELECT query to find the maximum recorded temperature for the 'Sea-Tac' location:

%%sql
select name, year, max(MAX) as maximum_temperature
from hudidb.noaa_hudi
where name = 'Sea-Tac'
group by 1,2

Run time travel queries

We can use time travel queries in SQL on Athena to analyze past data snapshots. For example:

%%sql
select name, year, max(MAX) as maximum_temperature
from hudidb.noaa_hudi timestamp as of '2023-12-01 23:53:43.100'
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

This query checks the Seattle Airport temperature data as of a specific time in the past. The timestamp clause lets us travel back without altering current data. Note that the timestamp value is specified as a string in format yyyy-MM-dd HH:mm:ss.fff.

Optimize query speed with clustering

To improve query performance, you can perform clustering on Hudi tables using SQL in Spark for Athena:

%%sql
CALL run_clustering(table => 'hudidb.noaa_hudi', order => 'name')

Compact tables

Compaction is a table service employed by Hudi specifically in Merge On Read (MOR) tables to merge updates from row-based log files to the corresponding columnar-based base file periodically to produce a new version of the base file. Compaction is not applicable to Copy On Write (COW) tables and only applies to MOR tables. You can run the following query in Spark for Athena to perform compaction on MOR tables:

%%sql
CALL run_compaction(op => 'run', table => 'hudi_table_mor');

Drop the table and database

Run the following Spark SQL to remove the Hudi table you created and associated data from the Amazon S3 location:

%%sql
DROP TABLE hudidb.noaa_hudi PURGE

Run the following Spark SQL to remove the database hudidb:

%%sql
DROP DATABASE hudidb

To learn about all the operations you can perform on Hudi tables using Spark for Athena, refer to SQL DDL and Procedures in the Hudi documentation.

Working with Linux foundation Delta Lake tables

Next, we show how you can use SQL on Spark for Athena to create, analyze, and manage Delta Lake tables.

Set up a notebook session

In order to use Delta Lake in Spark for Athena, while creating or editing a session, select Linux Foundation Delta Lake by expanding the Apache Spark properties section.

This image shows the Delta Lake properties set while creating Spak session in Athena.

For steps, see Editing session details or Creating your own notebook.

The code used in this section should be available in the SparkSQL_delta.ipynb file to follow along.

Create a database and Delta Lake table

In this section, we create a database in the AWS Glue Data Catalog. Using following SQL, we can create a database called deltalakedb:

%%sql
CREATE DATABASE deltalakedb

Next, in the database deltalakedb, we create a Delta Lake table called noaa_delta pointing to a location in Amazon S3 where we will load the data. Run the following statement and replace the location s3://<your-S3-bucket>/<prefix>/ with your S3 bucket and prefix:

%%sql
CREATE TABLE deltalakedb.noaa_delta(
station string,
date string,
latitude string,
longitude string,
elevation string,
name string,
temp string,
temp_attributes string,
dewp string,
dewp_attributes string,
slp string,
slp_attributes string,
stp string,
stp_attributes string,
visib string,
visib_attributes string,
wdsp string,
wdsp_attributes string,
mxspd string,
gust string,
max string,
max_attributes string,
min string,
min_attributes string,
prcp string,
prcp_attributes string,
sndp string,
frshtt string)
USING delta
PARTITIONED BY (year string)
LOCATION 's3://<your-S3-bucket>/<prefix>/noaadelta/'

Insert data into the table

We use an INSERT INTO statement to populate the table by reading data from the sparkblogdb.noaa_pq table created in the previous post:

%%sql
INSERT INTO deltalakedb.noaa_delta select * from sparkblogdb.noaa_pq

You can also use CREATE TABLE AS SELECT to create a Delta Lake table and insert data from a source table in one query.

Query the Delta Lake table

Now that the data is inserted in the Delta Lake table, we can start analyzing it. Let’s run a Spark SQL to find the minimum recorded temperature for the 'SEATTLE TACOMA AIRPORT, WA US' location:

%%sql
select name, year, max(MAX) as minimum_temperature
from deltalakedb.noaa_delta
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

Update data in the Delta lake table

Let’s change the station name 'SEATTLE TACOMA AIRPORT, WA US' to 'Sea–Tac'. We can run an UPDATE statement on Spark for Athena to update the records of the noaa_delta table:

%%sql
UPDATE deltalakedb.noaa_delta
SET name = 'Sea-Tac'
WHERE name = 'SEATTLE TACOMA AIRPORT, WA US'

We can run the previous SELECT query to find the minimum recorded temperature for the 'Sea-Tac' location, and the result should be the same as earlier:

%%sql
select name, year, max(MAX) as minimum_temperature
from deltalakedb.noaa_delta
where name = 'Sea-Tac'
group by 1,2

Compact data files

In Spark for Athena, you can run OPTIMIZE on the Delta Lake table, which will compact the small files into larger files, so the queries are not burdened by the small file overhead. To perform the compaction operation, run the following query:

%%sql
OPTIMIZE deltalakedb.noaa_delta

Refer to Optimizations in the Delta Lake documentation for different options available while running OPTIMIZE.

Remove files no longer referenced by a Delta Lake table

You can remove files stored in Amazon S3 that are no longer referenced by a Delta Lake table and are older than the retention threshold by running the VACCUM command on the table using Spark for Athena:

%%sql
VACUUM deltalakedb.noaa_delta

Refer to Remove files no longer referenced by a Delta table in the Delta Lake documentation for options available with VACUUM.

Drop the table and database

Run the following Spark SQL to remove the Delta Lake table you created:

%%sql
DROP TABLE deltalakedb.noaa_delta

Run the following Spark SQL to remove the database deltalakedb:

%%sql
DROP DATABASE deltalakedb

Running DROP TABLE DDL on the Delta Lake table and database deletes the metadata for these objects, but doesn’t automatically delete the data files in Amazon S3. You can run the following Python code in the notebook’s cell to delete the data from the S3 location:

import boto3

s3 = boto3.resource('s3')
bucket = s3.Bucket('<your-S3-bucket>')
bucket.objects.filter(Prefix="<prefix>/noaadelta/").delete()

To learn more about the SQL statements that you can run on a Delta Lake table using Spark for Athena, refer to the quickstart in the Delta Lake documentation.

Conclusion

This post demonstrated how to use Spark SQL in Athena notebooks to create databases and tables, insert and query data, and perform common operations like updates, compactions, and time travel on Hudi, Delta Lake, and Iceberg tables. Open table formats add ACID transactions, upserts, and deletes to data lakes, overcoming limitations of raw object storage. By removing the need to install separate connectors, Spark on Athena’s built-in integration reduces configuration steps and management overhead when using these popular frameworks for building reliable data lakes on Amazon S3. To learn more about selecting an open table format for your data lake workloads, refer to Choosing an open table format for your transactional data lake on AWS.


About the Authors

Pathik Shah is a Sr. Analytics Architect on Amazon Athena. He joined AWS in 2015 and has been focusing in the big data analytics space since then, helping customers build scalable and robust solutions using AWS analytics services.
Raj Devnath is a Product Manager at AWS on Amazon Athena. He is passionate about building products customers love and helping customers extract value from their data. His background is in delivering solutions for multiple end markets, such as finance, retail, smart buildings, home automation, and data communication systems.

Consuming private Amazon API Gateway APIs using mutual TLS

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/consuming-private-amazon-api-gateway-apis-using-mutual-tls/

This post is written by Thomas Moore, Senior Solutions Architect and Josh Hart, Senior Solutions Architect.

A previous blog post explores using Amazon API Gateway to create private REST APIs that can be consumed across different AWS accounts inside a virtual private cloud (VPC). Private cross-account APIs are useful for software vendors (ISVs) and SaaS companies providing secure connectivity for customers, and organizations building internal APIs and backend microservices.

Mutual TLS (mTLS) is an advanced security protocol that provides two-way authentication via certificates between a client and server. mTLS requires the client to send an X.509 certificate to prove its identity when making a request, together with the default server certificate verification process. This ensures that both parties are who they claim to be.

mTLS connection process

The mTLS connection process illustrated in the diagram above:

  1. Client connects to the server.
  2. Server presents its certificate, which is verified by the client.
  3. Client presents its certificate, which is verified by the server.
  4. Encrypted TLS connection established.

Customers use mTLS because it offers stronger security and identity verification than standard TLS connections. mTLS helps prevent man-in-the-middle attacks and protects against threats such as impersonation attempts, data interception, and tampering. As threats become more advanced, mTLS provides an extra layer of defense to validate connections.

Implementing mTLS increases overhead for certificate management, but for applications transmitting valuable or sensitive data, the extra security is important. If security is a priority for your systems and users, you should consider deploying mTLS.

Regional API Gateway endpoints have native support for mTLS but private API Gateway endpoints do not support mTLS, so you must terminate mTLS before API Gateway. The previous blog post shows how to build private mTLS APIs using a self-managed verification process inside a container running an NGINX proxy. Since then, Application Load Balancer (ALB) now supports mTLS natively, simplifying the architecture.

This post explores building mTLS private APIs using this new feature.

Application Load Balancer mTLS configuration

You can enable mutual authentication (mTLS) on a new or existing Application Load Balancer. By enabling mTLS on the load balancer listener, clients are required to present trusted certificates to connect. The load balancer validates the certificates before allowing requests to the backends.

Application Load Balancer mTLS configuration

There are two options available when configuring mTLS on the Application Load Balancer: Passthrough mode and Verify with trust store mode.

In Passthrough mode, the client certificate chain is passed as an X-Amzn-Mtls-Clientcert HTTP header for the application to inspect for authorization. In this scenario, there is still a backend verification process. The benefit in adding the ALB to the architecture is that you can perform application (layer 7) routing, such as path-based routing, allowing more complex application routing configurations.

In Verify with trust store mode, the load balancer validates the client certificate and only allows clients providing trusted certificates to connect. This simplifies the management and reduces load on backend applications.

This example uses AWS Private Certificate Authority but the steps are similar for third-party certificate authorities (CA).

To configure the certificate Trust Store for the ALB:

  1. Create an AWS Private Certificate Authority. Specify the Common Name (CN) to be the domain you use to host the application at (for example, api.example.com).
  2. Export the CA using either the CLI or the Console and upload the resulting Certificate.pem to an Amazon S3 bucket.
  3. Create a Trust Store, point this at the certificate uploaded in the previous step.
  4. Update the listener of your Application Load Balancer to use this trust store and select the required mTLS verification behavior.
  5. Generate certificates for the client application against the private certificate authority, for example using the following commands:
openssl req -new -newkey rsa:2048 -days 365 -keyout my_client.key -out my_client.csr

aws acm-pca issue-certificate –certificate-authority-arn arn:aws:acm-pca:us-east-1:111122223333:certificate-authority/certificate_authority_id–csr fileb://my_client.csr –signing-algorithm “SHA256WITHRSA” –validity Value=365,Type=”DAYS” –template-arn arn:aws:acm-pca:::template/EndEntityCertificate/V1

aws acm-pca get-certificate -certificate-authority-arn arn:aws:acm-pca:us-east-1:111122223333:certificate-authority/certificate_authority_id–certificate-arn arn:aws:acm-pca:us-east-1:account_id:certificate-authority/certificate_authority_id/certificate/certificate_id–output text

For more details on this part of the process, see Use ACM Private CA for Amazon API Gateway Mutual TLS.

Private API Gateway mTLS verification using an ALB

Using the ALB Verify with trust store mode together with API Gateway can enable private APIs with mTLS, without the operational burden of a self-managed proxy service.

You can use this pattern to access API Gateway in the same AWS account, or cross-account.

Private API Gateway mTLS verification using an ALB

The same account pattern allows clients inside the VPC to consume the private API Gateway by calling the Application Load Balancer URL. The ALB is configured to verify the provided client certificate against the trust store before passing the request to the API Gateway.

If the certificate is invalid, the API never receives the request. A resource policy on the API Gateway ensures that can requests are only allowed via the VPC endpoint, and a security group on the VPC endpoint ensures that it can only receive requests from the ALB. This prevents the client from bypassing mTLS by invoking the API Gateway or VPC endpoints directly.

Cross-account private API Gateway mTLS using AWS PrivateLink.

The cross-account pattern using AWS PrivateLink provides the ability to connect to the ALB endpoint securely across accounts and across VPCs. It avoids the need to connect VPCs together using VPC Peering or AWS Transit Gateway and enables software vendors to deliver SaaS services to be consumed by their end customers. This pattern is available to deploy as sample code in the GitHub repository.

The flow of a client request through the cross-account architecture is as follows:

  1. A client in the consumer application sends a request to the producer API endpoint.
  2. The request is routed via AWS PrivateLink to a Network Load Balancer in the consumer account. The Network Load Balancer is a requirement of AWS PrivateLink services.
  3. The Network Load Balancer uses an Application Load Balancer-type Target Group.
  4. The Application Load Balancer listener is configured for mTLS in verify with trust store mode.
  5. An authorization decision is made comparing the client certificate to the chain in the certificate trust store.
  6. If the client certificate is allowed the request is routed to the API Gateway via the execute-api VPC Endpoint. An API Gateway resource policy is used to allow connections only via the VPC endpoint.
  7. Any additional API Gateway authentication and authorization is performed, such as using a Lambda authorizer to validate a JSON Web Token (JWT).

Using the example deployed from the GitHub repo, this is the expected response from a successful request with a valid certificate:

curl –key my_client.key –cert my_client.pem https://api.example.com/widgets 

{“id”:”1”,”value”:”4.99”}

When passing an invalid certificate, the following response is received:

curl: (35) Recv failure: Connection reset by peer

Custom domain names

An additional benefit to implementing the mTLS solution with an Application Load Balancer is support for private custom domain names. Private API Gateway endpoints do not support custom domain names currently. But in this case, clients first connect to an ALB endpoint, which does support a custom domain. The sample code implements private custom domains using a public AWS Certificate Manager (ACM) certificate on the internal ALB, and an Amazon Route 53 hosted DNS zone. This allows you to provide a static URL to consumers so that if the API Gateway is replaced the consumer does not need to update their code.

Certificate revocation list

Optionally, as another layer of security, you can also configure a certificate revocation list for a trust store on the ALB. Revocation lists allow you to revoke and invalidate issued certificates before their expiry date. You can use this feature to off-boarding customers or denying compromised credentials, for example.

You can add the certificate revocation list to a new or existing trust store. The list is provided via an Amazon S3 URI as a PEM formatted file.

Conclusion

This post explores ways to provide mutual TLS authentication for private API Gateway endpoints. A previous post shows how to achieve this using a self-managed NGINX proxy. This post simplifies the architecture by using the native mTLS support now available for Application Load Balancers.

This new pattern centralizes authentication at the edge, streamlines deployment, and minimizes operational overhead compared to self-managed verification. AWS Private Certificate Authority and certificate revocation lists integrate with managed credentials and security policies. This makes it easier to expose private APIs safely across accounts and VPCs.

Mutual authentication and progressive security controls are growing in importance when architecting secure cloud-based workloads. To get started, visit the GitHub repository.

For more serverless learning resources, visit Serverless Land.