Tag Archives: serverless

Designing Serverless Integration Patterns for Large Language Models (LLMs)

Post Syndicated from Chris McPeek original https://aws.amazon.com/blogs/compute/designing-serverless-integration-patterns-for-large-language-models-llms/

This post is written by Josh Hart, Principal Solutions Architect and Thomas Moore, Senior Solutions Architect

This post explores best practice integration patterns for using large language models (LLMs) in serverless applications. These approaches optimize performance, resource utilization, and resilience when incorporating generative AI capabilities into your serverless architecture.

Overview of serverless, LLMs and example use case

Organizations of all shapes and sizes are harnessing LLMs to build generative AI applications to deliver new customer experiences. Serverless technologies such as AWS Lambda, AWS Step Functions and Amazon API Gateway enable you to move from idea to market faster without thinking about servers. The pay-for-use billing model also allows for increased agility at an optimal cost.

The examples in this post leverage Amazon Bedrock, a fully managed service to access foundation models (FMs). The same principles apply to LLMs hosted on other platforms such as Amazon SageMaker. Amazon Bedrock allows developers to consume LLMs via an API without the complexities of infrastructure management. Amazon SageMaker is a fully managed service to build, train and deploy machine learning models.

The example use-case in this post is leveraging LLMs to create compelling marketing content for the launch of a new family SUV. Images of the vehicle were pre-generated using Amazon Titan Image Generator in Amazon Bedrock, which are shown below.

Three different images of a new family SUV generated by Amazon Titan Image Generator.

Example use case images generated using Titan Image Generator

As organizations adopt LLMs to power generative AI applications, serverless architectures offer an attractive approach for rapid development and cost-effective scaling. The following sections explore several serverless integration patterns to build cost-effective, performant, and fault-tolerant generative AI applications.

Direct AWS Lambda call

Architecture diagram showing AWS Lambda invoking Amazon Bedrock using the InvokeModel API call.

Direct call to Amazon Bedrock from AWS Lambda

The simplest serverless integration pattern is directly calling Bedrock in Lambda using the AWS SDK. Below is an example Lambda function using the Python SDK (boto3), calling the Bedrock InvokeModel API.

import json
import boto3
brt = boto3.client(service_name='bedrock-runtime')

def lambda_handler(event, context):
    body = json.dumps({
        "anthropic_version": "bedrock-2023-05-31",
        "max_tokens": 1000,
        "messages": [{
            "role": "user",
            "content": [{
                "type": "text",
                "text":"Create a 500 word car advert given these images and the following specification: \n {}".format(event['spec'])
            },
            {
                "type": "image",
                "source": {
                    "type": "base64",
                    "media_type": "image/jpeg",
                    "data": event['image']
                }
            }]
        }]
    })

    modelId = 'anthropic.claude-3-sonnet-20240229-v1:0'
    accept = 'application/json'
    contentType = 'application/json'
    response = brt.invoke_model(body=body, modelId=modelId, accept=accept, contentType=contentType)
    response_body = json.loads(response.get('body').read())

    return {
        'statusCode': 200,
        'body': response_body["content"][0]["text"]
    }

The above code requires the Lambda function execution role to have the correct AWS Identity and Access Management (IAM) permissions to Amazon Bedrock, specifically the bedrock:InvokeModel action.

The example uses the Anthropic Claude 3 Sonnet LLM and the Anthropic Claude Messages API for the payload. The InvokeModel call is synchronous and will therefore wait for a response from the LLM. Depending on the model and prompt, the call can take several seconds. Ensure your Lambda function timeout is set appropriately. In most cases it will need to be increased from the default of 3 seconds.

The boto3 client has a default timeout of 60 seconds. Depending on the use case, you may need to increase the boto3 client timeout as shown in the sample code below.

from botocore.config import Config
# Set the read timeout to 600 seconds (10 minutes)
config = Config(read_timeout=600)

# Create the Bedrock client with the custom read timeout configuration
boto3_bedrock = boto3.client(service_name='bedrock-runtime', config=config)

When working with LLMs, the generated text is often substantial, leading to increased response times or even timeouts. Amazon Bedrock provides the ability to stream responses using InvokeModelWithResponseStream which allows you to process and consume the generated text in chunks as it becomes available. This enables a faster response to the client and allows at least a partial response even if a timeout occurs.

When using response streaming with Lambda functions you should set the boto3 read_timeout to a lower value than the function execution timeout, meaning you will have the option to return at least some content. In some situations this is preferred to no response at all. For example, you might set your Lambda function timeout to 2 minutes and your boto3 read timeout to 90 seconds. This gives you 30 seconds to take additional action. Depending on the failure scenario, you might take various actions:

  • Transient errors such as rate limiting or service quotas: Consider backing off and retrying the request or load-balancing requests to another region with cross-region inference.
  • Timeout errors when the boto3 read timeout is hit: Decide whether to retry the request with a simplified prompt (or a shorter response length) or return a partial response.

Prompt chaining with AWS Step Functions    

The direct Lambda pattern works well for simple single-prompt inference. Accomplishing complex tasks with LLMs requires a technique called prompt chaining, where tasks are broken down into smaller well-defined subtask prompts and each prompt is fed to the LLM in a defined order.

Prompt chaining inside a single Lambda function can be time consuming, and may exceed the maximum Lambda timeout of 15 minutes in some cases. AWS Step Functions can be used to solve this issue by orchestrating calls to LLMs. Bedrock has an optimized integration for Step Functions which allows you to use Run as Job (.sync). This integration pattern means Step Functions will wait for the InvokeModel request to complete before progressing to the next state. With Step Functions Standard Workflows you only pay for state transitions, which reduces the cost for Lambda idle wait time.

The below example shows prompt chaining with Step Functions using direct integrations only. The example eliminates the need of custom Lambda code.

Workflow diagram for AWS Step Functions showing an example prompt chain to generate different text content for showroom vehicles.

Prompt chaining using AWS Step Functions

  1. The user input (vehicle description) is passed to Amazon Bedrock via the Step Functions optimized integration.
  2. The generated output of the InvokeModel API call is passed via the ResultPath to the next step.
  3. The state machine sets the input of the next step based on the output of the previous step using the Pass state.
  4. The output of each inference request continues to be passed between each step in the workflow.
  5. The last step runs an inference request and the final result is returned as the output of the state machine.

Another advantage to using AWS Step Functions to invoke the LLM is the built-in error handling. Step Functions can be setup to automatically retry on error and allows you to configure a backoff rate and add jitter to help control throttling. No custom coding is required.

View of the different error handling options in AWS Step Functions for a particular action. Including internal, max attempts, backoff rate, max delay and jitter.

Built-in error handling options for an action in an AWS Step Functions workflow

Handling throttling is particularly important when you are approaching the Bedrock service quota limits, such as the number of requests processed per minute for a particular model. Be aware that some limits are hard limits and cannot be adjusted. See the Bedrock service quotas documentation for the latest information.

Parallel prompts with AWS Step Functions

The performance of the application can be improved by breaking down tasks into smaller sub-tasks and running them in parallel. This can dramatically decrease the overall response time, especially for larger models and complex prompts. In the following example, parallel processing reduced the total execution time of the state machine from 30.8 seconds to 19.2 seconds, an improvement of 37.7% when compared to the same steps run in sequence.

The below example uses the Step Functions parallel state to perform Bedrock InvokeModel actions in parallel.

Example workflow showing prompt chaining using the AWS Step Functions parallel state.

Prompt chaining example using parallel state in AWS Step Functions

  1. The user input (vehicle description) is passed to Amazon Bedrock via the Step Functions optimized integration.
  2. The Step Functions parallel state allows branching logic to perform multiple steps in parallel.
  3. Complex inference tasks are run in parallel to reduce end-to-end execution time.
  4. Shorter tasks can be combined to balance branch execution time with longer running tasks.
  5. The generated output is combined and the final response returned.

In addition to the parallel state, the Step Functions map state can be used to run the same action multiple times in parallel with different inputs. For example if you wanted to generate marketing materials for 100 vehicles with data stored in Amazon S3 you could run the above workflow nested in a distributed map state.

Result caching

Generating text using LLMs can be a computationally intensive and a time-consuming process, especially for complex prompts or long content generation. To improve performance and reduce latency, caching should be used where possible by storing and reusing previously generated responses. This concept is explored in detail in Mastering LLM Caching for Next-Generation AI.

Caching can be implemented at different levels within your application architecture, each with its own advantages and trade-offs. Here are some examples:

  1. Caching inside the Lambda execution environment: if your Lambda function receives repeated prompts or inputs, you can store these results inside memory or the /tmp directory of a warmed execution environment.
  2. External caching services: to overcome the limitations of in-memory caching and leverage more robust caching solutions, you can integrate with external services to store previous results like Amazon ElastiCache (for Redis or Memcached) or Amazon DynamoDB.

The example below uses a Step Functions workflow to check for a cached response in DynamoDB before invoking the model. The cache key in this case could be the LLM prompt. This helps to reduce costs whilst improving performance. The example generates custom vehicle descriptions based on a particular persona, for example to focus on safety features and luggage space for a family, or performance specifications for a motorsport enthusiast.

Example AWS Step Functions workflow that uses Amazon DynamoDB to store and retrieve previously generated LLM responses.

Example AWS Step Functions that uses Amazon DynamoDB to cache LLM responses

When implementing caching, it is crucial to consider factors such as cache invalidation strategies, cache size limitations, and data consistency requirements. For example, if your LLM generates dynamic or personalized content, caching may not be suitable, as the responses could be stale or incorrect for different users or contexts.

Conclusion

This post explored integration patterns for consuming LLMs in serverless applications, enabling an efficient and reliable next generation experience for customers. Single-prompt inference can be achieved with AWS Lambda using the AWS SDK.

Responses from LLMs can be large and often leads to manipulating large text responses in memory, especially for Retrieval-Augmented Generation (RAG) use cases. It’s therefore important to select an optimal memory configuration for your function, and the recommended way to do this is using the AWS Lambda Power Tuning.

When more complex prompt chaining is required it’s best practice to explore Step Functions as a way to reduce idle wait time and avoid being limited by the Lambda 15 minute timeout. Step Functions also bring the benefits of an optimized integration for Bedrock, as well as the ability to handle errors and run tasks in parallel.

Remember that model choice is also an important consideration to balance cost, performance and output capabilities. This is discussed further in Choose the best foundational model for your AI applications.

To find more serverless patterns using Amazon Bedrock take a look at Serverless Land.
Empowering builders: introducing the Dev Alliance and Workers Launchpad Cohort #4

Post Syndicated from Melissa Kargiannakis original https://blog.cloudflare.com/launchpad-cohort4-dev-starter-pack

Today we’re announcing the Dev Starter Pack, an alliance of innovative tools for developers to get started with discounts and free services. We’re also excited to share an update on our Workers Launchpad Program.

Creating from the ground up often means spending countless hours piecing together the right development stack, navigating different pricing models, and managing growing costs — all of which can take your focus away from what truly matters: building your product and growing your business.

Introducing Dev Starter Pack: the tools you need to start building your startup

Hey! Dani Grant here, one of the first PMs at Cloudflare and co-founder of Jam.dev. Ten years ago (during 2014’s Birthday Week), Cloudflare launched Universal SSL, making SSL free on the Internet for the first time, and in one night doubling the size of the encrypted web.

I was a college student back then, and I immediately became enraptured by Cloudflare’s mission: helping build a better Internet. As part of this mission, Cloudflare has developed powerful tools typically accessible only to Internet giants, oftentimes offering them for free to developers and individuals alike. Heck yeah! I joined Cloudflare in January 2015, and 5 years after that, co-founded a developer tool company called Jam, inspired by the impact that I saw building tools for developers could have while at Cloudflare.

It’s now 10 years later, and a lot has changed –– “software ate the world” and it’s now powering all aspects of our lives, from health to finances to how we work. It’s more important than ever to empower every developer with the best tools available, because the faster we build software, the sooner people’s experiences improve.

Today we’re thrilled to announce the Dev Starter Pack, an alliance of like-minded dev tool companies giving away their services for free, or heavily discounting them for developers who want to start companies and build the future.

Not only does this stack include all the tools you need to build a startup, it also includes all the tools you need to build AI-powered features. We believe that the next wave of startups will be AI-native, as AI becomes as ubiquitous as the electricity that powers the servers.

We haven’t even scratched the surface of what’s possible with AI, and we hope this launch gets developers closer to solving the challenges of building non-deterministic software.

If you’re a software engineer, and you want to build a project or a company and need an off the shelf stack of dev tools to get started, go to devstarterpack.io to start using all of these tools.

Each provider is offering developers a heavily discounted or even free plan to get started building. You can redeem these services by either using the special code “devstarterpack” or selecting “Dev Starter Pack” while applying to relevant programs.

We welcome more tools to join the alliance — this is just the beginning. If you are building a developer tool and would like to include your product in the Dev Starter Pack, let us know here, so we can include you. 

What will you build?

We are very excited to see what you will build. Please share with us in Cloudflare’s Discord and community forum, so we can support you however it makes sense.

Software developers are changing the world, and we believe in providing support to help you make an even greater impact. If you’re looking for additional funding or support, check out Cloudflare’s Launchpad for developers turned founders building startups.


Introducing Workers Launchpad Cohort #4

Melissa and Chris from the Cloudflare for Startups team here. Our team is blown away by what customers are demonstrating on the Developer Platform. Just a few weeks ago, our Workers Launchpad Cohort #3 wrapped up. On Demo Day, customers demoed their applications built on Cloudflare, spanning AI, dev tools, IaaS, observability, SaaS, media, and beyond. We’re incredibly proud of Cohort #3 participants, and we look forward to their continued success with Cloudflare.

Following Demo Day of Workers Launchpad Cohort #3, we’ve been excited to receive a surge of new applications from startups around the world. These startups are pushing the boundaries of innovation, particularly in areas like observability, PaaS, AI, automation, e-commerce, and other industries. Many startups that applied this go-around demonstrated that they’ve built some great applications on Cloudflare, and today, we’re excited to announce the accepted participants for our upcoming Workers Launchpad Cohort #4.

Let’s take a look at what Cohort #4 participants are building in their own words:

Adster

Hyperscale revenue powered by real-time data intelligence and AI

Almeta

Predict customer behavior on your website

Best Parents

Disruptive educational travel marketplace for Gen Z under 18

Comigo

Companion app to make therapy an engaging daily practice

Datastrato

A unified data catalog for generative AI infrastructure

Equimake

Create professional 3D projects without technical experience

Evefan

Your own Internet scale events infrastructure

Eventuall

Connecting stars with their fans in paid meet & greets and virtual experiences

Fermat

No-code solution to deploy AI models as internal tools

Fiberplane

Development tool that uses observability data to help test and debug APIs

Firetiger

An engineering observability tool that operates at scale inside customer infrastructure

Flightcast

Video-first podcast hosting & distribution

FlightLevel Technologies

AI Analytics and Footage in the aviation industry.

Gitlip

Powerful, collaborative and lightweight computing platform based on Git

GrackerAI

AI-powered organic growth engine for cybersecurity B2B SaaS

Hackernoon

Community-driven blogging network read by millions of technologists

Hanabi.REST

Prompt to REST API with AI-driven building, testing, and deployment

Infrastack

Next-gen application intelligence and observability platform for developers

June

AI productivity companion

Leed AI

Combined marketing workflows, website, and customer journey for a seamless, AI-accelerated experience

lookbk

Make the Internet more shoppable, starting with fashion on socials

Materialized Intelligence

Data-intensive inference solutions

Maxint

Multi-platform money management powered by AI

Midio

Visual tool to build software and AI agents

NikaPlanet

Transformative geospatial analytics experience with Google Colab, QGIS, ChatGPT, and Miro in one solution

NotHotDog

AI-Powered API Testing Tool

Outerbase

View, edit, query, and visualize your data with AI

Procureezy

AI procurement platform to empower hardware engineers to source smarter and launch sooner

Proma

Process management and automation platform to get work done fast

Render Better

Increase e-commerce revenue by optimizing your site speed, automatically

Sherpo

AI-first no-code platform to build and sell digital content

Speak_

AI platform to surface top talent by evaluating candidates against custom criteria

Tightknit

Embedded community engagement platform built for SaaS

Tinfoil

Powerful analytics with cryptographic privacy guarantees

Velvet

AI gateway to monitor, evaluate, and optimize features

Webstudio

An advanced visual site builder that connects to any headless CMS

Zipr

Streamlined visitor management

The Cloudflare team is ecstatic to work with the amazing participants of Cohort #4. If you want to follow along on Cohort #4’s journey, be sure to follow @CloudflareDev on X and join our Developer Discord server.

Are you a startup building on Cloudflare? Apply for Cohort #5!

Let’s Architect! Building multi-tenant SaaS systems

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-building-multi-tenant-saas-systems/

Software as a Service (SaaS) applications offer a transformative solution for businesses worldwide, delivering on-demand software solutions to a global audience. However, building a successful SaaS platform demands on meticulous architectural planning, especially given the inherent challenges of multi-tenancy. It’s also essential to ensure that each tenant’s data remains isolated and protected from unauthorized access and that multi-tenant systems are cost-optimized and can sustain the scaling of the SaaS business provider.

In this blog post, we will explore some of the key elements and best practices for designing and deploying secure and efficient SaaS systems on AWS.

Building cost-optimized multi-tenant SaaS architectures

Cost is a key factor to consider when we design new systems. Multi-tenancy requires teams to think beyond the basics of auto scaling, adopting strategies to allow their architecture to support a complex cost-scaling challenges. In this session, the speaker covers some design patterns for distributed systems to support the continually evolving scale needs of the environment, while optimizing the cost of the infrastructure.

The architectural model chosen for deploying multi-tenant systems—pooled, siloed, or mixed—significantly influences the cost optimization strategy. Each approach offers distinct trade-offs in terms of resource allocation, scalability, and cost efficiency.

Figure 1. The architectural model chosen for deploying multi-tenant systems—pooled, siloed, or mixed—significantly influences the cost-optimization strategy. Each approach offers distinct trade-offs in terms of resource allocation, scalability, and cost efficiency.

Take me to this video

Well-Architected SaaS Lens

The SaaS Lens for the AWS Well-Architected Framework empowers customers to assess and enhance their cloud-based architectures, fostering a deeper understanding of the business implications of their design choices. By bringing together technical leadership and diverse teams to discuss strategies for improving various aspects of the system, the AWS Well-Architected Framework facilitates collaborative decision-making. Moreover, the AWS account team can provide valuable support in conducting these assessments, offering expert guidance and insights. The AWS SaaS Lens specifically focuses on how to design, deploy, and architect multi-tenant SaaS application workloads within the AWS Cloud.

The microservices running in a multi-tenant environment must be able to reference and apply tenant context within each service. At the same time, it’s also our goal to limit the degree to which developers need to introduce any tenant awareness into their code.

Figure 2. The microservices running in a multi-tenant environment must be able to reference and apply tenant context within each service. At the same time, it’s also our goal to limit the degree to which developers need to introduce any tenant awareness into their code.

Take me to this well-architected framework

SaaS anywhere: Designing distributed multi-tenant architectures

Not every SaaS provider has the luxury of running all the moving parts of their solution within their own infrastructure. SaaS teams might support a range of diverse system models, where architectures might include customer-hosted data, edge deployment for parts of the application, and on-premises components. In this session, you can learn the strategies to support the complexities of this distributed model without undermining the resilience, operational efficiency, and agility goals of your solution. The video covers how this influences the onboarding, deployment, and profile management of the SaaS environment.

In this architectural pattern, tenants are demanding to have the ML workload in their environment. So, the SaaS provider only manages the SaaS Control plane where tenants deploy the application plane in their environment, including the ML workload and the necessary components around it.

Figure 3. In this architectural pattern, tenants are demanding to have the ML workload in their environment. So, the SaaS provider only manages the SaaS control plane where tenants deploy the application plane in their environment, including the ML workload and the necessary components around it.

Take me to this video

Deploying multi-tenant SaaS applications on Amazon ECS and AWS Fargate

Containers are frequently employed in multi-tenant SaaS environments to enhance scalability, isolation, and resource efficiency. Developing such systems requires addressing multiple challenges, including tenant isolation, tenant on-boarding, tenant-specific metering, monitoring, and other factors related to multi-tenancy. This session explores how to effectively manage all of these aspects when deploying solutions on AWS Fargate.

Microservices architecture can enhance security isolation by dividing applications into smaller, independent services, reducing the potential impact of a breach.

Figure 4. Microservices architecture can enhance security isolation by dividing applications into smaller, independent services, reducing the potential impact of a breach.

Take me to this video

AWS Serverless SaaS Workshop

Serverless helps to create multi-tenant architectures thanks to services like AWS Lambda that isolate your business logic per request, making them the perfect companion to run a SaaS platform. This workshop provides a hands-on introduction to creating serverless multi-tenant SaaS applications, helping you get started and gain practical experience.

This is the high level architecture of the web application you will use in the AWS Serverless SaaS Workshop. In the labs, you will use this web application to add features that are needed to build this final SaaS application.

Figure 5. This is the high-level architecture of the web application you will use in the AWS Serverless SaaS Workshop. In the labs, you will use this web application to add features that are needed to build this final SaaS application.

Take me to this workshop

See you next time!

Thanks for reading! Multi-tenant SaaS architectures require a careful design of your system. In this post, you have discovered key elements for properly designing your next SaaS workloads. In the next blog, we will talk about modern data architectures.

To revisit any of our previous posts or explore the entire series, visit the Let’s Architect! page.

Startup Program revamped: build and grow on Cloudflare with up to $250,000 in credits

Post Syndicated from Christopher Rotas original https://blog.cloudflare.com/startup-program-250k-credits

Today, we’re pleased to offer startups up to $250,000 in credits to use on Cloudflare’s Developer Platform. This new credits system will allow you to clearly see usage and associated fees to plan for a predictable future after the $250,000 in credits have been used up or after one year, whichever happens first.

You can see eligibility criteria and apply to the start-up program here. 

What can you use the credits for?

Credits can be applied to all Developer Platform products, as well as Argo and Cache Reserve. Moreover, we provide participants with up to three Enterprise-level domains, which includes CDN, DDoS, DNS, WAF, Zero Trust, and other security and performance products that a participant can enable for their website.

Developer tools and building on Cloudflare

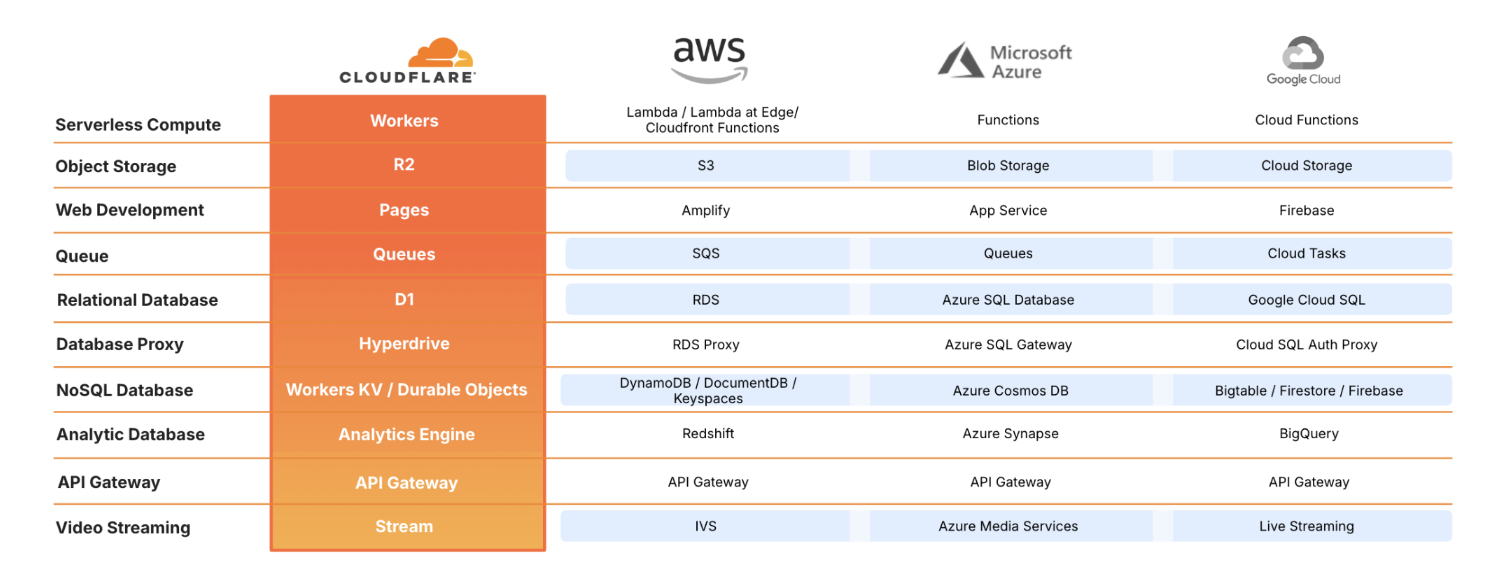
You can use credits for Cloudflare Developer Platform products, including those listed in the table below.

Note: credits for the Cloudflare Startup Program apply to Cloudflare products only, this table is illustrative of similar products in the market.

Speed and performance with Cloudflare

We know that founders need all the help they can get when starting their businesses. Beyond the Developer Platform, you can also use the Startup Program for our speed and performance products. Getting customers where they need to go within milliseconds on your website or application is the difference between closing a sale or not. You can test your speed here and learn how to optimize your speed and performance here with solutions like: Images, Argo, and Early Hints.

Security from Cloudflare

But, wait, there’s more: beyond the Developer Platform products and speed tools, you can also use Cloudflare’s many security features through the Startup Program as well. These include Web Application Firewall (WAF), DDoS Alerts, bundled protection plans, and more. The Startup Program also includes Zero Trust solutions. Learn how others are securing their technology and tools with Cloudflare Zero Trust.

For more inspiration, check out our Built with Cloudflare site, which highlights what other startups are building. 

Who can use the credits?

Eligibility criteria can be found here and include:

  • Companies building a software-based product or service

  • Founded within the last 5 years (2019-2024)

  • Have between $50,000 - $5,000,000 in funding

    • Note that for startups who have not yet raised at least $50,000, there may be other opportunities for lower credit amounts. Please apply with the promo code “BOOTSTRAPPED” if you haven’t raised $50,000 yet, but are interested in the Cloudflare Startup Program

  • Have a LinkedIn profile, valid website, and email address

  • Bonus criteria that adds to your application: being part of an approved accelerator

What will you build?

We’re excited to see what you will build. Please share what you’re up to with us so that we can help you however it makes sense. If you’re actively using Cloudflare’s Developer Platform, we’d love to hear more about what you’re building and share it on our Built with Cloudflare site.

Are you a startup looking for additional support, resources, or access to funding? Apply for our Workers Launchpad Program! The program runs for a few months, and in addition to the Startup Program, participants get access to hands-on bootcamp sessions, Solutions Architect office hours, introductions to VCs, and the opportunity to present at Demo Day.

Why does Cloudflare support founders and startups? 

Founders and developers face enough challenges without having to worry about incurring egregious costs to test technology and start building in the earliest days. You have the world at your fingertips and should be empowered to build and create without limitations. Invest money in your innovation, not in the infrastructure and technology that supports it.

The Startup Program understands this founder experience deeply, as the team is made up of former founders. Cloudflare is committed to programs like this to empower founders building the next big thing. Offering up to $250,000 in credits will allow folks to leverage even more of what we have to offer: a developer experience that removes friction, saves money, and gets applications spun up in hours, not days. 

We want to support founders from everywhere on earth.

Be bold and keep building! Follow @CloudflareDev and join our Developer Discord server.

Are you a startup building on Cloudflare? Apply here!

Building a three-tier architecture on a budget

Post Syndicated from Adam Nemeth original https://aws.amazon.com/blogs/architecture/building-a-three-tier-architecture-on-a-budget/

AWS customers often look for ways to run their systems within or under budget, avoiding unnecessary costs. This post offers practical advice on designing scalable and cost-efficient three-tier architectures by using serverless technologies within the AWS Free Tier.

With AWS, you can start small and scale cost-effectively as your business demand increases. You can begin with minimal investments by using the Free Tier to build a minimum viable product (MVP). Then you can expand resources as your user base grows and your needs evolve, and transition to a full-fledged, large-scale application.

In this blog post, you will learn how to build a three-tier architecture that predominantly relies on AWS service usage within the Free Tier, resulting in a highly affordable architecture.

Note: The Free Tier offerings mentioned within this blog post are subject to change. Always check the AWS Free Tier page for the most current information.

Background: Understanding the AWS Free Tier

The Free Tier provides users with access to a range of AWS services at no cost within predefined monthly usage limits. This offering helps users to run experimentation, development, and even production workloads without charges. The Free Tier is available for more than 100 AWS products today, including Amazon Simple Storage Service (Amazon S3), Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Relational Database Service (Amazon RDS). Depending on the product, there are three types of Free Tier offers:

  • Free trials – Short-term trial offers that start when the first usage begins. After the trial period expires, you pay standard service rates.
  • 12 months free – Offers available to new AWS customers for 12 months following their sign-up date. After the 12-month free term expires, you pay standard service rates.
  • Always free – Offers available to both existing and new AWS customers indefinitely.

For example, the AWS Lambda Free Tier includes one million free requests per month and 400,000 GB-seconds of compute time per month usable for functions across both x86 and AWS Graviton processors. The AWS Lambda Free Tier falls under the always free category.

Walkthrough: Three-tier architecture on AWS

Cost efficiency is a prominent advantage of using AWS serverless services. These services decrease the need for provisioning and managing servers, reducing operational overhead and labor costs. Serverless services like AWS Lambda and Amazon API Gateway use a pay-as-you-go model. This way, you only pay for the resources you consume, providing significant savings compared to maintaining idle infrastructure. Serverless technologies also feature automatic scaling and built-in high availability to increase agility and optimize costs.

A three-tier architecture is a popular implementation of a multi-tier architecture and consists of a presentation tier, business logic tier, and data tier. A three-tier architecture separates an application’s functionality into distinct layers (presentation, business logic, and data) to enable scalability, modularity, and flexibility in software development. This type of architecture is suitable for building a wide range of applications such as web applications, enterprise systems, and mobile apps.

The following image is an example of a three-tier architecture fully built with AWS serverless services. In this example, users authenticate and navigate to the website in the presentation tier. They call APIs, which invoke Lambda functions at the business logic tier. Data is stored in DynamoDB at the data tier.

Users authenticate through Amazon Cognito and navigate to the website in the presentation tier. They call APIs, which invoke Lambda functions at the business logic tier. Data is stored in DynamoDB at the data tier.

Figure 1: Example of a three-tier architecture on AWS

In the following sections, we explore how to use AWS serverless services within the Free Tier to build a similar architecture.

Note: The Free Tier offerings mentioned within this blog post are subject to change. Always check the AWS Free Tier page for the most current information.

Presentation tier

The presentation tier is where your users interact with your offering, such as a webpage or an app. You can use the following services within the Free Tier to build your presentation tier.

AWS service How you can use it Free Tier details*
Amazon S3 Host static and dynamic assets, like a React Single Page Application (SPA), and distribute them to your end users. For the first year, you get 5 GB of standard storage, 20,000 GET requests and 2,000 PUT requests. See Amazon S3 pricing for details.
Amazon CloudFront Use with Amazon S3 for a faster and more performant distribution of your assets to end users. CloudFront gives you access to the AWS content delivery network with more than 410 points of presence worldwide. CloudFront includes an Always Free Tier, with 1 TB of data transfer out to the internet per month and 10 million HTTP(S) requests per month. See Amazon CloudFront pricing for details.
Amazon Cognito Use Amazon Cognito user pools to authenticate your users. You can also integrate Amazon Cognito within your application’s UI for a seamless login experience. Amazon Cognito has an Always Free Tier, including up to 50,000 monthly active users. It also includes 10 GBs of cloud sync storage and 1 million sync operations per month, valid for the first 12 months after sign-up. See Amazon Cognito pricing for details.

*as of September 2024

Business logic tier

The business logic tier is where code translates user actions to application functionality. You can use the following services within the Free Tier to build your business logic tier.

AWS service How you can use it Free Tier details*
Amazon API Gateway Build a front door to your application’s backend by creating REST or WebSocket APIs. Get 1 million monthly API calls for free, valid for the first 12 months after sign-up. See Amazon API Gateway pricing for details.
AWS Lambda Use AWS Lambda for a serverless compute environment that integrates with API Gateway. You can embed your business logic into functions that run on AWS without the need for you to run and manage infrastructure. The Always Free Tier offers 1 million free requests and 400,000 GB-seconds of compute time per month. See AWS Lambda pricing for details.

*as of September 2024

Data tier

The data tier is where your data is stored. You can use the following service within the Free Tier to build your data tier.

AWS service How you can use it Free Tier details*
Amazon DynamoDB Use this serverless NoSQL database for storing data and tracking transactions. In the context of a three-tier architecture, DynamoDB stores and manages the application’s data, providing reliable and secure data access to the business logic tier. The Always Free Tier offers 25GB of free storage, with up to 200 million requests, 25 write capacity units (WCUs), and 25 read capacity units (RCUs) per month.

*as of September 2024

Walkthrough: Monitoring your usage to avoid unexpected charges

If you use consolidated billing or AWS Organizations, the Free Tier usage accumulates at the management account level. Each management account receives one quota of the Free Tier.

To monitor your Free Tier usage and avoid unexpected charges, you can use the following resources:

The following image shows an example of the Free Tier page in the AWS Billing and Cost Management console.

Free Tier dashboard showing usage limit, current usage, and forecasted usage for in-scope services.

Figure 2: AWS Free Tier view in the Cost and Usage Report

We also recommend configuring a zero spend budget within the AWS Billing and Cost Management console. With this budget, you receive notifications when your usage exceeds the Free Tier limits, helping you to avoid unexpected charges. The following image shows an example of this budget setup.

Choose budget type menu with Use a template and Zero spend budget both selected.

Figure 3: Zero spend budget

Conclusion

In this post, we explored how to use AWS serverless services within the Free Tier to build a three-tier application. We also explored how to monitor your Free Tier usage. The Free Tier offers a chance to experiment and develop without additional costs, helping businesses minimize infrastructure expenses early on. AWS serverless architectures bring benefits like cost savings, flexibility, and scalability.

Beyond using services within the Free Tier, you can further optimize the cost of your AWS serverless application. For instance, to prevent incurring unnecessary inter-Region data transfer costs, we recommend starting with a single Region deployment for your application.

To learn more about the Free Tier and which services it offers, check out the AWS Free Tier FAQs.

Additionally, you can explore various architectural patterns for AWS serverless multi-tier architectures and the Serverless Full Stack WebApp Starter Kit to create scalable and cost-effective solutions on AWS.

Efficiently processing batched data using parallelization in AWS Lambda

Post Syndicated from Chris Munns original https://aws.amazon.com/blogs/compute/efficiently-processing-batched-data-using-parallelization-in-aws-lambda/

This post is written by Anton Aleksandrov, Principal Solutions Architect, AWS Serverless

Efficient message processing is crucial when handling large data volumes. By employing batching, distribution, and parallelization techniques, you can optimize the utilization of resources allocated to your AWS Lambda function. This post will demonstrate how to implement parallel data processing within the Lambda function handler, maximizing resource utilization and potentially reducing invocation duration and function concurrency requirements.

Overview

AWS Lambda integrates with various event sources, such as Amazon SQS, Apache Kafka, or Amazon Kinesis, using event-source mappings. When you configure an event-source mapping, Lambda continuously polls the event source and automatically invokes your function to process the retrieved data. Lambda makes more invocations of your function as the number of messages it reads from the event source increases. This can increase the utilized function concurrency and consume the available concurrency in your account. Click the links to learn more about how Lambda consumes messages from SQS queues and Kinesis streams.

To improve the data processing throughput, you can configure event-source mapping batch window and batch size. These settings ensure that your function is invoked only when a sufficient number of messages have accumulated in the event source. For example, if you configure a batch size of 100 messages and a batch window of 10 seconds, Lambda will invoke your function when either 100 messages have accumulated or 10 seconds have elapsed, whichever happens first.

Event source mapping event batching

Event source mapping event batching

By processing messages in batches, rather than individually, you can improve throughput and optimize costs by reducing the number of polling requests to event sources and the number of function invocations. For instance, processing a million messages without batching would require one million function invocations, but configuring a batch size of 100 messages can reduce the number of invocations to 10,000.

Optimizing batch processing within the Lambda execution environment

Each Lambda execution environment processes one event per invocation. With batching enabled, the event object Lambda sends to the function handler contains an array of messages retrieved and batched by the event-source mapping. Once an execution environment starts processing an event object containing a batch of messages, it won’t handle additional invocations until the current one is complete. However, simply iterating over the array of messages and processing them one by one may not fully utilize the allocated compute resources. This can lead to underutilized or idle compute resources, like CPU capacity, and hence longer overall processing times.

Underutilized Lambda environments

Underutilized Lambda environments

Underutilization of compute resources can be generally caused by two things – non-CPU-intensive blocking tasks, such as sending HTTP requests and waiting for responses, and single-threaded processing when you have more than one vCPU core. To address these concerns and maximize resource utilization, you can implement your functions to process data in parallel. This allows more efficient utilization of the allocated compute capacity, reducing invocation duration, time spent idle, and the total concurrency required. In addition, when you allocate more than 1.8GB of memory to your function, it also gets more than one vCPU, which allows threads to land on separate cores for even better performance and true parallel processing.

Improved concurrency in Lambda environment

Improved concurrency in Lambda environment

When processing messages sequentially with a low compute utilization rate, reducing memory allocation may seem intuitive to save costs. This, however, can result in slower performance due to less CPU capacity being allocated. When your function is parallelizing data processing within the execution environment, you’re getting a higher compute utilization rate, and since raising the memory allocation also provides additional CPU capacity, it can lead to better performance. Use the Lambda Power Tuning tool to find the optimal memory configuration, balancing cost with performance.

Understanding the Lambda execution environment lifecycle

After processing an invocation, the Lambda execution environment is “frozen” by the Lambda service. Lambda runtime considers the invocation complete and “freezes” the execution environment when your function handler returns.

When the Lambda service is looking for an execution environment to process a new incoming invocation, it will first try to “thaw” and use any available execution environments that were previously “frozen”. This cycle repeats until the execution environment is eventually shut down.

Lambda worker lifecycle over time

Lambda worker lifecycle over time

Implementing parallel processing within the Lambda execution environment

You can implement parallel processing by running multiple threads in your function handler, but if those threads are still running when the handler returns, then they will be “frozen” together with the execution environment until the next invocation. This can lead to unexpected behavior, where the execution environment is “thawed” to process a new invocation, however, it still has background threads running and processing data from previous invocations. If you do not handle this properly, the behavior can cascade across multiple invocations, leading to delayed or unfinished processing and complicated debugging.

Threads frozen before finishing

Threads frozen before finishing

To address this concern, you need to ensure that the background threads you spawn in the function handler are done processing data before returning from the handler. All threads spawned within a particular invocation must complete within the same invocation in order not to spill over to subsequent invocations. This is illustrated in the following diagram. You can see threads start and end within the same invocation, and only once all threads have finished, the function handler returns.

Threads returning before end of invoke

Threads returning before end of invoke

Sample code

Programming languages offer diverse techniques and terminology for parallel and concurrent processing. Java employs multi-threading and thread pools. Node.js, though single-threaded, provides event loop and promises (for async programming), as well as child processes and worker threads (for actual multi-threading). Python supports both multi-threading (subject to Global Interpreter Lock) and multi-processing. Concurrent routines is another technique gaining attention.

The following sample is provided for illustration purposes only and is based on Node.js promises running concurrently. The sample code uses a language-agnostic term “worker” to denote a unit of parallel processing. Your specific parallelization implementation depends on your choice of runtime language and frameworks. AWS recommends you use battle-tested frameworks like Powertools for AWS Lambda that implement concurrent batch processing when possible. Regardless of the programming language, it is crucial to ensure all background threads/workers/promises/routines/tasks spawned by the function handler are completed within the same invocation before the handler returns.

Sample implementation with Node.js

const NUMBER_OF_WORKERS = 4;

export const handler = async (event) => {
    const workers = []; 
    const messages = event.Records;
    
    // For handling partial batch processing errors
    const batchItemFailures = [];

    for (let i=0; i<NUMBER_OF_WORKERS;i++){
        // No await here! The waiting will happen later
        const worker = spawnWorker(i, messages, batchItemFailures);
        workers.push(worker);
    }
    
    // This line is crucial. This is where the handler
    // waits for all workers to complete their tasks
    const processingResults = await Promise.allSettled(workers);
    console.log('All done!');

    // Return messageIds of all messages that failed 
    // to process in order to retry
    return {batchItemFailures};
};

async function spawnWorker(id, messages, batchItemFailures){
    console.log(`worker.id=${id} spawning`);
    while (messages.length>0){
        const msg = messages.shift();
        console.log(`worker.id=${id} processing message`);
        try {
            // A blocking, but not CPU-intensive operation 
            await processMessage(msg);
        } catch (err){
            // If message processing failed, add it to 
            // the list of batch item failures
            batchItemFailures.push({ itemIdentifier: msg.messageId});
        }
    }
}

See the sample code and AWS Cloud Development Kit (CDK) stack at github.com.

Testing results

The following chart illustrates a Lambda function processing messages using an SQS event-source mapping. After enabling message processing with 4 workers, the invocation duration and concurrent executions dropped to 1/4th of the previous value, while still processing the same number of messages per second. Thanks to parallelization, the new function is faster and requires less concurrency.

Function performance dashboard

Function performance dashboard

Looking at the invocation log, you can see that the function handler has spawned four workers, and all of them were completed before the handler returned the result. You can also see that although the handler received 20 items, with each item taking 200ms to process, the overall duration is only 1000ms. This is because items were processed in parallel (20 items * 200ms / 4 workers = 1000ms total processing time).

START RequestId: (redacted)  Version: $LATEST
2024-06-18T03:18:03.049Z    INFO    Got messages from SQS
2024-06-18T03:18:03.049Z    INFO    messages.length=20
2024-06-18T03:18:03.049Z    INFO    worker.id=0 spawning
2024-06-18T03:18:03.049Z    INFO    worker.id=0 processing message
2024-06-18T03:18:03.049Z    INFO    worker.id=1 spawning
2024-06-18T03:18:03.049Z    INFO    worker.id=1 processing message
2024-06-18T03:18:03.050Z    INFO    worker.id=2 spawning
2024-06-18T03:18:03.050Z    INFO    worker.id=2 processing message
2024-06-18T03:18:03.050Z    INFO    worker.id=3 spawning
2024-06-18T03:18:03.050Z    INFO    worker.id=3 processing message
2024-06-18T03:18:03.250Z    INFO    worker.id=0 processing message
2024-06-18T03:18:03.250Z    INFO    worker.id=1 processing message
(redacted for brevity)
2024-06-18T03:18:03.852Z    INFO    worker.id=1 processing message
2024-06-18T03:18:03.852Z    INFO    worker.id=2 processing message
2024-06-18T03:18:03.852Z    INFO    worker.id=3 processing message
2024-06-18T03:18:04.052Z    INFO    All done!
END RequestId: (redacted)
REPORT RequestId: (redacted) Duration: 1004.48 ms

Considerations

  • The technique and samples described in this post assume unordered message processing. In case you use ordered event sources, such as SQS FIFO Queues, and require preserving message order, you will need to address that in your implementation code. One technique might be creating a separate thread for each messageGroupId.
  • While providing performance and cost benefits, multi-threading and parallel processing is an advanced technique that requires proper error handling. Lambda supports partial batch responses, where you can report back to the event source that specific messages from the batch failed to be processed so they can be retried. You can collect failed message IDs from each thread and return them as your function handler response. This is illustrated in the sample above. See Handling errors for an SQS event source in Lambda and Best Practices for implementing partial batch responses for additional details.

Conclusion

Efficiently processing large volumes of data implies efficient resource utilization. When processing batches of messages from event sources, validate whether your function would benefit from parallel or concurrent processing within the function handler thus increasing the compute capacity utilization rate. With a high compute capacity utilization rate, you can allocate more memory to your function, thus getting more CPU allocated as well, for faster and more efficient processing. Use frameworks like Powertools for AWS Lambda that implement concurrent batch processing when possible, and use the Lambda Power Tuning tool to find the best memory configuration for your functions, balancing performance and cost.

For more serverless learning resources, visit Serverless Land.

How Wesfarmers Health implemented upstream event buffering using Amazon SQS FIFO

Post Syndicated from Robbie Cooray original https://aws.amazon.com/blogs/architecture/how-wesfarmers-health-implemented-upstream-event-buffering-using-amazon-sqs-fifo/

Customers of all sizes and industries use Software-as-a-Service (SaaS) applications to host their workloads. Most SaaS solutions take care of maintenance and upgrades of the application for you, and get you up and running in a relatively short timeframe. Why spend time, money, and your precious resources to build and maintain applications when this could be offloaded?

However, working with SaaS solutions can introduce new requirements for integration. This blog post shows you how Wesfarmers Health was able to introduce an upstream architecture using serverless technologies in order to work with integration constraints.

At the end of the post, you will see the final architecture and a sample repository for you to download and adjust for your use case.

Let’s get started!

Consent capture problem

Wesfarmers Health used a SaaS solution to capture consent. When capturing consent for a user, order guarantee and delivery semantics become important. Failure to correctly capture consent choice can lead to downstream systems making non-compliant decisions. This can end up in penalties, financial or otherwise, and might even lead to brand reputation damage.

In Wesfarmers’ case, the integration options did not support a queue with order guarantee nor exactly-once processing. This meant that, with enough load and chance, a user’s preference might be captured incorrectly. Let’s look at two scenarios where this could happen.

In both of these scenarios, the user makes a choice, and quickly changes their mind. These are considered two discreet events:

  1. Event 1 – User confirms “yes.”
  2. Event 2 – User then quickly changes their mind to confirm “no.”

Scenario 1: Incorrect order

In this scenario, two events end up in a queue with no order guarantee. Event 2 might be processed before Event 1, so although the user provided a “no,” the system has now captured a “yes.” This is now considered a non-compliant consent capture.

Animation showing messages processed in the wrong order

Figure 1. Animation showing messages processed in the wrong order

Scenario 2 – events processed multiple times

In this scenario, perhaps due to the load, Event 1 was transmitted twice, once before and once after Event 2, due to at least once processing. In this scenario, the user’s record could be updated three times, first with Event 1 with “yes,” then Event 2 with “no,” then again with retransmitted Event 1 with “yes,” which ultimately ends up with a “yes,” also considered a non-compliant consent capture.

Animation showing messages processed multiple times

Figure 2. Animation showing messages processed multiple times

How did Amazon SQS and Amazon DynamoDB help with order?

With Amazon Amazon Simple Queue Service (Amazon SQS), queues come in two flavors: standard and first-in-first-out (FIFO). Standard queues provide best effort ordering and at-least once processing with high throughput, whereas FIFO delivers order and processes exactly once with relatively low throughput, as shown in Figure 3.

Animation showing FIFO queue processing in the correct order

Figure 3. Animation showing FIFO queue processing in the correct order

In Wesfarmers Health’s scenario with relatively few events per user, it made sense to deploy a FIFO queue to deliver messages in the order they arrived and also have them delivered once for each event (see more details on quotas at Amazon SQS FIFO queue quotas).

Wesfarmers Health also employed the use of message group IDs to parallelize all users using a unique userID. This means that they can guarantee order and exactly-once processing at the user level, while processing all users in parallel, as shown in Figure 4.

Animation showing a FIFO queue partitioned per user, in the correct order per user

Figure 4. Animation showing a FIFO queue partitioned per user, in the correct order per user

The buffer implementation

Wesfarmers Health also opted to buffer messages for the same user in order to minimize race conditions. This was achieved by employing an Amazon DynamoDB table to capture the timestamp of the last message that was processed. For this, Wesfarmers Health designed the DynamoDB table shown in Figure 5.

Example DynamoDB schema with messageGroupId based on user, and TTL

Figure 5. Example DynamoDB schema with messageGroupId based on user, and TTL

The messageGroupId value corresponds to a unique identifier for a user. The time-to-live (TTL) value serves dual functions. First, the TTL is the value of the Unix timestamp for the last time a message from a specific user was processed, plus the desired message buffer interval (for example, 60 seconds). It also serves a secondary function of allowing DynamoDB to remove obsolete entries to minimize table size, thus improving cost for certain DynamoDB operations.

In between the Amazon SQS FIFO queue and the Amazon DynamoDB table sits an AWS Lambda function that listens to all events and transmits to the downstream SaaS solution. The main responsibility of this Lambda function is to check the DynamoDB table for the last processed timestamp for the user before processing the event. If, by chance, a user event for the user was already processed within the buffer interval, then that event is sent back to the queue with a visibility timeout that matches the interval, so that the user events for that user is not processed until the buffer interval is passed.

Amazon DynamoDB table and AWS Lambda function introducing the buffer

Figure 6. Amazon DynamoDB table and AWS Lambda function introducing the buffer

Final architecture

Figure 7 shows the high-level architecture diagram that powers this integration. When users send their consent events, it is sent to the SQS FIFO queue first. The AWS Lambda function determines, based on the timestamp stored in the DynamoDB table, whether to process it or delay the message. Once the outcome is determined, the function passes through the event downstream.

Final architecture diagram

Figure 7. Final architecture diagram

Why serverless services were used

The Wesfarmers Health Digital Innovations team is strategically aligned towards a serverless first approach where appropriate. This team builds, maintains, and owns these solutions end-to-end. Using serverless technologies, the team gets to focus on delivering business outcomes while leaving the undifferentiated heavy lifting of managing infrastructure to AWS.

In this specific scenario, the number of requests for consent is sporadic. With serverless technologies, you pay as you go. This is a great use case for workloads that have requests fluctuate throughout the day, providing the customer a great option to be cost efficient.

The team at Wesfarmers Health has been on the serverless journey for a while, and are quite mature in developing and managing these workloads in a production setting using best practices mentioned above and employing the AWS Well Architected Framework to guide their solutions.

Conclusion

SaaS solutions are a great mechanism to move fast and reduce the undifferentiated heavy lifting of building and maintaining solutions. However, integrations play a crucial part as to how these solutions work with your existing ecosystem.

Using AWS services, you can build these integration patterns that is fit for purpose, for your unique requirements.

AWS Serverless Patterns is a great place to get started to see what other patterns exist for your use case.

Next steps

Check out the repository hosted on AWS Patterns that sets up this architecture. You can review, modify, and extend it for your own use case.

AWS Lambda introduces recursive loop detection APIs

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/aws-lambda-introduces-recursive-loop-detection-apis/

This post is written by James Ngai, Senior Product Manager, AWS Lambda, and Aneel Murari, Senior Specialist SA, Serverless.

Today, AWS Lambda is announcing new recursive loop detection APIs that allow you to set recursive loop detection configuration on individual Lambda functions. This allows you to turn off recursive loop detection on functions that intentionally use recursive patterns, avoiding disruption of these workloads. You can use these APIs to avoid disruption to any intentionally recursive workflows as Lambda expands support of recursive loop detection to other AWS services.

Overview

AWS Lambda functions are triggered in response to events generated by various AWS services. These Lambda functions may interact with other AWS services by invoking the corresponding service APIs. Typically, the service and resource that generates the triggering event is distinct from the service and resource that the Lambda function calls. However, due to coding errors or configuration issues, there may be situations where these two resources are the same, leading to an infinite or recursive loop. Such misconfigurations can result in runaway workloads, which can incur unplanned usage and charges to your AWS account. For example, a Lambda function processes messages from an Amazon Simple Notification Service (SNS) topic but then puts the resulting notification back to the same SNS topic. This causes an infinite loop.

Lambda provides a built-in preventative guardrail that detects and stops functions running in a recursive or infinite loop between Lambda, Amazon Simple Queue Service (SQS), and SNS. This feature, known as recursive loop detection, is enabled by default for all Lambda functions. This serves as a protective mechanism against unintended usage and unexpected billing from runaway workloads.

Lambda uses an AWS X-Ray trace header primitive called “lineage” to track the number of times a function has been invoked with an event. When your function code sends an event using a supported AWS SDK version, Lambda increments the counter in the lineage header. If your function is then invoked with the same triggering event more than 16 times, Lambda stops the next invocation for that event and emits an Amazon CloudWatch RecursiveInvocationsDropped metric. If the function is invoked synchronously, Lambda returns a RecursiveInvocationException to the caller. For asynchronous invocations, Lambda sends the event to a dead-letter queue or on-failure destination if one is configured.

You do not need to configure active X-Ray tracing for this feature to work. For more information on this feature and an example scenario, please refer to Detecting and stopping recursive loops in AWS Lambda functions.

Although AWS generally discourages this practice due to the possibility of runaway workloads, some customers intentionally employ recursive patterns in their workflows. Previously, customers that run workloads that intentionally use recursive patterns could only opt-out of recursive loop detection on a per-account basis by contacting AWS Support. With these new APIs, customers can selectively opt-out of recursive loop detection on individual functions while maintaining this preventative guardrail for the remaining functions in their account that do not use recursive code.

Today we are introducing two new API actions for recursive loop detection:

  • GetFunctionRecursiveConfig returns details about a function’s recursive loop detection configuration.
  • PutFunctionRecursiveConfig sets the recursive loop detection configuration for a function. By default, recursive loop detection is turned ON for all functions.

How to use the new recursive loop detection APIs

You can configure recursive loop detection for Lambda functions through the Lambda Console, the AWS CLI, or Infrastructure as Code tools like AWS CloudFormation, AWS Serverless Application Model (AWS SAM), or AWS Cloud Development Kit (CDK). This new configuration option is supported in AWS SAM CLI version 1.123.0 and CDK v2.153.0.

If you turn recursive loop detection off for a function, the metric for RecursiveInvocationsDropped is no longer emitted for that function.

Turning off recursive loop detection on your function means that Lambda no longer prevents recursive invocations caused by misconfiguration. This may lead to unexpected usage and billing to your AWS account. You should explore alternate ways of architecting your workload that do not use recursive patterns. AWS recommends you exercise caution when turning off this guardrail feature.

Setting recursive loop detection configuration on a function using the Lambda Console

You can get recursive loop detection configuration in the AWS Lambda console:

  1. In the AWS Lambda Console, navigate to the Functions page. Select the function that uses intentionally recursive patterns.
  2. Select Configuration. You can find recursive loop detection controls under the Concurrency and recursion detection section.
  3. Recursive loop detection controls in the Lambda console

    Recursive loop detection controls in the Lambda console

  4. Recursive loop detection is turned on by default for all functions. You can change the recursive loop detection configuration of a function by choosing Edit.
  5. To turn off recursive loop detection for a function, select Allow recursive loops and select Save.
Setting to allow recursive loops

Setting to allow recursive loops

Setting recursive loop detection configuration using the AWS CLI

You can get the current recursion loop detection configuration of a Lambda function by using the following CLI command:

aws lambda get-function-recursion-config \
--region $AWS_REGION \
--function-name $FUNCTION_NAME

You can update the recursion loop detection configuration for a Lambda function by using the following CLI command:

aws lambda put-function-recursion-config \
--region $AWS_REGION \
--function-name $FUNCTION_NAME \
--recursive-loop Allow|Terminate

Make sure to set appropriate values for AWS_REGION and FUNCTION_NAME in the previous commands. Setting the put-function-recursion-config parameter to Allow turns off the default behavior of detecting recursive loops. Set this value to Terminate to switch back to default behavior.

Setting recursive loop detection configuration using AWS CloudFormation

You can control the recursive loop detection configuration for a Lambda function by setting the RecursiveLoop resource property in CloudFormation. Setting the value of this property to Allow turns off the default behavior of automatically detecting recursive loops. Set this property to Terminate if you want to switch it back to the default behavior. The following CloudFormation snippet shows RecursiveLoop set to Allow.

LambdaFunction:
    Type: AWS::Lambda::Function                                                                                                                                                                                    
    Properties:                                                                                                                                                                                       
      Code:                                                                                                                                                                                          
        S3Bucket:S3_BUCKET                                                                                                                                                                            
        S3Key: S3_KEY      
      Handler: com.example.App::handleRequest                                                                                                                                                        
      MemorySize: 1024
      Role:                                                                                                                                                                                          
        Fn::GetAtt:                                                                                                                                                                                  
        - LambdaFunctionRole                                                                                                                                                                         
        - Arn                                                                                                                                                                               
      Runtime: java17
      RecursiveLoop : Allow                                                                                                                                                                                                                                                                           
      Timeout: 20                                                                                                                                                                        
      TracingConfig:                                                                                                                                                                               
        Mode: Active                                                                                                                                                                                        

Extending recursive loop detection to additional AWS services

Today, recursive loop detection detects and stops loops between Lambda, SQS, and SNS after approximately 16 invocations. Lambda plans to extend support for recursive loop detection to additional AWS services. Using the APIs, you can turn off recursive loop detection for specific functions that use recursive patterns so that they are not impacted when Lambda expands recursive loop detection to additional AWS services in the future.

One way you can identify functions that use recursive patterns is by using the CloudWatch metric RecursiveInvocationsDropped.

  1. Set a CloudWatch alarm on all Lambda functions for the CloudWatch metric RecursiveInvocationsDropped. Configure the alarm to trigger when the metric is greater than a threshold of zero. Refer to CloudWatch documentation to set alarms. You can use the following CLI command to set this alarm:
  2. aws cloudwatch put-metric-alarm --alarm-name lambda-recursive-alarm --metric-name RecursiveInvocationsDropped --namespace AWS/Lambda --statistic Sum --period 60 --threshold 0 --comparison-operator GreaterThanOrEqualToThreshold --evaluation-periods 1 --alarm-actions $arn-of-sns-notification-topic
  3. When Lambda detects recursive invocations, it will emit the RecursiveInvocationsDropped metric, which will trigger the alarm. Note that Lambda will only detect and stop recursive invocations if all the services within the loop support recursive loop detection.
  4. Navigate to the CloudWatch Console and determine which function has emitted the RecursiveInvocationsDropped metric. On the Browse tab, under Metrics, choose to view metrics By Function Name and search for RecursiveInvocationsDropped. This will list all functions that have emitted that metric.
  5. RecursiveInvocationsDropped metric

    RecursiveInvocationsDropped metric

  6. Determine if recursion is the intended pattern for that function. If so, use the recursive loop detection API to turn off recursive loop detection for this function.

Conclusion

Lambda recursive loop detection automatically detects and stops recursive invocations between Lambda and supported services, preventing runaway workloads. In most cases, you should architect your workloads to avoid any recursive loops. In rare and special circumstances, you may want to turn off the default behavior on a case-by-case basis. The recursive loop detection APIs allow you to set recursive loop detection configuration on individual functions.

This feature is available in all AWS Regions where Lambda supports recursive loop detection.

To learn more about these APIs, refer to the AWS Lambda API Reference.

For more serverless learning resources, visit Serverless Land

Unlock scalable analytics with a secure connectivity pattern in AWS Glue to read from or write to Snowflake

Post Syndicated from Caio Montovani original https://aws.amazon.com/blogs/big-data/unlock-scalable-analytics-with-a-secure-connectivity-pattern-in-aws-glue-to-read-from-or-write-to-snowflake/

In today’s data-driven world, the ability to seamlessly integrate and utilize diverse data sources is critical for gaining actionable insights and driving innovation. As organizations increasingly rely on data stored across various platforms, such as Snowflake, Amazon Simple Storage Service (Amazon S3), and various software as a service (SaaS) applications, the challenge of bringing these disparate data sources together has never been more pressing.

AWS Glue is a robust data integration service that facilitates the consolidation of data from different origins, empowering businesses to use the full potential of their data assets. By using AWS Glue to integrate data from Snowflake, Amazon S3, and SaaS applications, organizations can unlock new opportunities in generative artificial intelligence (AI), machine learning (ML), business intelligence (BI), and self-service analytics or feed data to underlying applications.

In this post, we explore how AWS Glue can serve as the data integration service to bring the data from Snowflake for your data integration strategy, enabling you to harness the power of your data ecosystem and drive meaningful outcomes across various use cases.

Use case

Consider a large ecommerce company that relies heavily on data-driven insights to optimize its operations, marketing strategies, and customer experiences. The company stores vast amounts of transactional data, customer information, and product catalogs in Snowflake. However, they also generate and collect data from various other sources, such as web logs stored in Amazon S3, social media platforms, and third-party data providers. To gain a comprehensive understanding of their business and make informed decisions, the company needs to integrate and analyze data from all these sources seamlessly.

One crucial business requirement for the ecommerce company is to generate a Pricing Summary Report that provides a detailed analysis of pricing and discounting strategies. This report is essential for understanding revenue streams, identifying opportunities for optimization, and making data-driven decisions regarding pricing and promotions. After the Pricing Summary Report is generated and stored in Amazon S3, the company can use AWS analytics services to generate interactive BI dashboards and run one-time queries on the report. This allows business analysts and decision-makers to gain valuable insights, visualize key metrics, and explore the data in depth, enabling informed decision-making and strategic planning for pricing and promotional strategies.

Solution overview

The following architecture diagram illustrates a secure and efficient solution of integrating Snowflake data with Amazon S3, using the native Snowflake connector in AWS Glue. This setup uses AWS PrivateLink to provide secure connectivity between AWS services across different virtual private clouds (VPCs), eliminating the need to expose data to the public internet, which is a critical need for organizations.

BDB-4354-architecture

The following are the key components and steps in the integration process:

  1. Establish a secure, private connection between your AWS account and your Snowflake account using PrivateLink. This involves creating VPC endpoints in both the AWS and Snowflake VPCs, making sure data transfer remains within the AWS network.
  2. Use Amazon Route 53 to create a private hosted zone that resolves the Snowflake endpoint within your VPC. This allows AWS Glue jobs to connect to Snowflake using a private DNS name, maintaining the security and integrity of the data transfer.
  3. Create an AWS Glue job to handle the extract, transform, and load (ETL) process on data from Snowflake to Amazon S3. The AWS Glue job uses the secure connection established by the VPC endpoints to access Snowflake data. Snowflake credentials are securely stored in AWS Secrets Manager. The AWS Glue job retrieves these credentials at runtime to authenticate and connect to Snowflake, providing secure access management. A VPC endpoint enables you to securely communicate with this service without traversing the public internet, enhancing security and performance.
  4. Store the extracted and transformed data in Amazon S3. Organize the data into appropriate structures, such as partitioned folders, to optimize query performance and data management. We use a VPC endpoint enabled to securely communicate with this service without traversing the public internet, enhancing security and performance. We also use Amazon S3 to store AWS Glue scripts, logs, and temporary data generated during the ETL process.

This approach offers the following benefits:

  • Enhanced security – By using PrivateLink and VPC endpoints, data transfer between Snowflake and Amazon S3 is secured within the AWS network, reducing exposure to potential security threats.
  • Efficient data integration – AWS Glue simplifies the ETL process, providing a scalable and flexible solution for data integration between Snowflake and Amazon S3.
  • Cost-effectiveness – Using Amazon S3 for data storage, combined with the AWS Glue pay-as-you-go pricing model, helps optimize costs associated with data management and integration.
  • Scalability and flexibility – The architecture supports scalable data transfers and can be extended to integrate additional data sources and destinations as needed.

By following this architecture and taking advantage of the capabilities of AWS Glue, PrivateLink, and associated AWS services, organizations can achieve a robust, secure, and efficient data integration solution, enabling them to harness the full potential of their Snowflake and Amazon S3 data for advanced analytics and BI.

Prerequisites

Complete the following prerequisites before setting up the solution:

  1. Verify that you have access to AWS account with the necessary permissions to provision resources in services such as Route 53, Amazon S3, AWS Glue, Secrets Manager, and Amazon Virtual Private Cloud (Amazon VPC) using AWS CloudFormation, which lets you model, provision, and manage AWS and third-party resources by treating infrastructure as code.
  2. Confirm that you have access to Snowflake hosted in AWS with required permissions to run the steps to configure PrivateLink. Refer to Enabling AWS PrivateLink in the Snowflake documentation to verify the steps, required access level, and service level to set the configurations. After you enable PrivateLink, save the value of the following parameters provided by Snowflake to use in the next step in this post:
    1. privatelink-vpce-id
    2. privatelink-account-url
    3. privatelink_ocsp-url
    4. regionless-snowsight-privatelink-url
  3. Make sure you have a Snowflake user snowflakeUser and password snowflakePassword with required permissions to read from and write to Snowflake. The user and password are used in the AWS Glue connection to authenticate within Snowflake.
  4. If your Snowflake user doesn’t have a default warehouse set, you will need a warehouse name. We use snowflakeWarehouse as a placeholder for the warehouse name; replace it with your actual warehouse name.
  5. If you’re new to Snowflake, consider completing the Snowflake in 20 Minutes By the end of the tutorial, you should know how to create required Snowflake objects, including warehouses, databases, and tables for storing and querying data.

Create resources with AWS CloudFormation

This post includes a CloudFormation template for a quick setup of the base resources. You can review and customize it to suit your needs if needed. The CloudFormation template generates the following resources:

To create your resources, complete the following steps:

  1. Sign in to the AWS CloudFormation console.
  2. Choose Launch Stack to launch the CloudFormation stack.
  3. Provide the CloudFormation stack parameters:
    1. For PrivateLinkAccountURL, enter the value of the parameter privatelink-account-url obtained in the prerequisites.
    2. For PrivateLinkOcspURL, enter the value of the parameter privatelink_ocsp-url obtained in the prerequisites.
    3. For PrivateLinkVpceId, enter the value of the parameter privatelink-vpce-id obtained in the prerequisites.
    4. For PrivateSubnet1CIDR, enter the IP addresses for your private subnet 1.
    5. For PrivateSubnet2CIDR, enter the IP addresses for your private subnet 2.
    6. For PrivateSubnet3CIDR, enter the IP addresses for your private subnet 3.
    7. For PublicSubnet1CIDR, enter the IP addresses for your public subnet 1.
    8. For RegionlessSnowsightPrivateLinkURL, enter the value of the parameter regionless-snowsight-privatelink-url obtained in the prerequisites.
    9. For VpcCIDR, enter the IP addresses for your VPC.
  4. Choose Next.
  5. Select I acknowledge that AWS CloudFormation might create IAM resources.
  6. Choose Submit and wait for the stack creation step to complete.

After the CloudFormation stack is successfully created, you can see all the resources created on the Resources tab.

Navigate to the Outputs tab to see the outputs provided by CloudFormation stack. Save the value of the outputs GlueSecurityGroupId, VpcId, and PrivateSubnet1Id to use in the next step in this post.

BDB-4354-cfn-output

Update the Secrets Manager secret with Snowflake credentials for the AWS Glue connection

To update the Secrets Manager secret with user snowflakeUser, password snowflakePassword, and warehouse snowflakeWarehouse that you will use in the AWS Glue connection to establish a connection to Snowflake, complete the following steps:

  1. On the Secrets Manager console, choose Secrets in the navigation pane.
  2. Open the secret blog-glue-snowflake-credentials.
  3. Under Secret value, choose Retrieve secret value.

BDB-4354-secrets-manager

  1. Choose Edit.
  2. Enter the user snowflakeUser, password snowflakePassword, and warehouse snowflakeWarehouse for the keys sfUser, sfPassword, and sfWarehouse, respectively.
  3. Choose Save.

Create the AWS Glue connection for Snowflake

An AWS Glue connection is an AWS Glue Data Catalog object that stores login credentials, URI strings, VPC information, and more for a particular data store. AWS Glue crawlers, jobs, and development endpoints use connections in order to access certain types of data stores. To create an AWS Glue connection to Snowflake, complete the following steps:

  1. On the AWS Glue console, in the navigation pane, under Data catalog, choose Connections.
  2. Choose Create connection.
  3. For Data sources, search for and select Snowflake.
  4. Choose Next.

BDB-4354-sf-data-source

  1. For Snowflake URL, enter https://<privatelink-account-url>.

To obtain the Snowflake PrivateLink account URL, refer to parameters obtained in the prerequisites.

  1. For AWS Secret, choose the secret blog-glue-snowflake-credentials.
  2. For VPC, choose the VpcId value obtained from the CloudFormation stack output.
  3. For Subnet, choose the PrivateSubnet1Id value obtained from the CloudFormation stack output.
  4. For Security groups, choose the GlueSecurityGroupId value obtained from the CloudFormation stack output.
  5. Choose Next.

BDB-4354-sf-connection-setup

  1. In the Connection Properties section, for Name, enter glue-snowflake-connection.
  2. Choose Next.

BDB-4354-sf-connection-properties

  1. Choose Create connection.

Create an AWS Glue job

You’re now ready to define the AWS Glue job using the Snowflake connection. To create an AWS Glue job to read from Snowflake, complete the following steps:

  1. On the AWS Glue console, under ETL jobs in the navigation pane, choose Visual ETL.

BDB-4354-glue-studio

  1. Choose the Job details tab.
  2. For Name, enter a name, for example, Pricing Summary Report Job.
  3. For Description, enter a meaningful description for the job.
  4. For IAM Role, choose the role that has access to the target S3 location where the job is writing to and the source location from where it’s loading the Snowflake data and also to run the AWS Glue job. You can find this role in your CloudFormation stack output, named blog-glue-snowflake-GlueServiceRole-*.
  5. Use the default options for Type, Glue version, Language, Worker type, Number of workers, Number of retries, and Job timeout.
  6. For Job bookmark, choose Disable.
  7. Choose Save to save the job.

BDB-4354-glue-job-details

  1. On the Visual tab, choose Add nodes.

  1. For Sources, choose Snowflake.

  1. Choose Data source – Snowflake in the AWS Glue Studio canvas.
  2. For Name, enter Snowflake_Pricing_Summary.
  3. For Snowflake connection, choose glue-snowflake-connection.
  4. For Snowflake source, select Enter a custom query.
  5. For Database, enter snowflake_sample_data.
  6. For Snowflake query, add the following Snowflake query:
SELECT l_returnflag
    , l_linestatus
    , Sum(l_quantity) AS sum_qty
    , Sum(l_extendedprice) AS sum_base_price
    , Sum(l_extendedprice * (1 - l_discount)) AS sum_disc_price
    , Sum(l_extendedprice * (1 - l_discount) * (1 + l_tax)) AS sum_charge
    , Avg(l_quantity) AS avg_qty
    , Avg(l_extendedprice) AS avg_price
    , Avg(l_discount) AS avg_disc
    , Count(*) AS count_order
FROM tpch_sf1.lineitem
WHERE l_shipdate <= Dateadd(day, - 90, To_date('1998-12-01'))
GROUP BY l_returnflag
    , l_linestatus
ORDER BY l_returnflag
    , l_linestatus;

The Pricing Summary Report provides a summary pricing report for all line items shipped as of a given date. The date is within 60–120 days of the greatest ship date contained in the database. The query lists totals for extended price, discounted extended price, discounted extended price plus tax, average quantity, average extended price, and average discount. These aggregates are grouped by RETURNFLAG and LINESTATUS, and listed in ascending order of RETURNFLAG and LINESTATUS. A count of the number of line items in each group is included.

  1. For Custom Snowflake properties, specify Key as sfSchema and Value as tpch_sf1.
  2. Choose Save.

BDB-4354-glue-source-setup

Next, you add the destination as an S3 bucket.

  1. On the Visual tab, choose Add nodes.
  2. For Targets, choose Amazon S3.

  1. Choose Data target – S3 bucket in the AWS Glue Studio canvas.
  2. For Name, enter S3_Pricing_Summary.
  3. For Node parents, select Snowflake_Pricing_Summary.
  4. For Format, select Parquet.
  5. For S3 Target Location, enter s3://<YourBucketName>/pricing_summary_report/ (use the name of your bucket).
  6. For Data Catalog update options, select Create a table in the Data Catalog and on subsequent runs, update the schema and add new partitions.
  7. For Database, choose db_blog_glue_snowflake.
  8. For Table name, enter tb_pricing_summary.
  9. Choose Save.
  10. Choose Run to run the job, and monitor its status on the Runs tab.

You successfully completed the steps to create an AWS Glue job that reads data from Snowflake and loads the results into an S3 bucket using a secure connectivity pattern. Eventually, if you want to transform the data before loading it into Amazon S3, you can use AWS Glue transformations available in AWS Glue Studio. Using AWS Glue transformations is crucial when creating an AWS Glue job because they enable efficient data cleansing, enrichment, and restructuring, making sure the data is in the desired format and quality for downstream processes. Refer to Editing AWS Glue managed data transform nodes for more information.

Validate the results

After the job is complete, you can validate the output of the ETL job run in Athena, a serverless interactive analytics service. To validate the output, complete the following steps:

  1. On the Athena console, choose Launch Query Editor.
  2. For Workgroup, choose blog-workgroup.
  3. If the message “All queries run in the Workgroup, blog-workgroup, will use the following settings:” is displayed, choose Acknowledge.
  4. For Database, choose db_blog_glue_snowflake.
  5. For Query, enter the following statement:
SELECT l_returnflag
    , l_linestatus
    , sum_qty
    , sum_base_price
FROM db_blog_glue_snowflake.tb_pricing_summary
  1. Choose Run.

You have successfully validated your data for the AWS Glue job Pricing Summary Report Job.

Clean up

To clean up your resources, complete the following tasks:

  1. Delete the AWS Glue job Pricing Summary Report Job.
  2. Delete the AWS Glue connection glue-snowflake-connection.
  3. Stop any AWS Glue interactive sessions.
  4. Delete content from the S3 bucket blog-glue-snowflake-*.
  5. Delete the CloudFormation stack blog-glue-snowflake.

Conclusion

Using the native Snowflake connector in AWS Glue provides an efficient and secure way to integrate data from Snowflake into your data pipelines on AWS. By following the steps outlined in this post, you can establish a private connectivity channel between AWS Glue and your Snowflake using PrivateLink, Amazon VPC, security groups, and Secrets Manager.

This architecture allows you to read data from and write data to Snowflake tables directly from AWS Glue jobs running on Spark. The secure connectivity pattern prevents data transfers over the public internet, enhancing data privacy and security.

Combining AWS data integration services like AWS Glue with data platforms like Snowflake allows you to build scalable, secure data lakes and pipelines to power analytics, BI, data science, and ML use cases.

In summary, the native Snowflake connector and private connectivity model outlined here provide a performant, secure way to include Snowflake data in AWS big data workflows. This unlocks scalable analytics while maintaining data governance, compliance, and access control. For more information on AWS Glue, visit AWS Glue.


About the Authors

Caio Sgaraboto Montovani is a Sr. Specialist Solutions Architect, Data Lake and AI/ML within AWS Professional Services, developing scalable solutions according customer needs. His vast experience has helped customers in different industries such as life sciences and healthcare, retail, banking, and aviation build solutions in data analytics, machine learning, and generative AI. He is passionate about rock and roll and cooking, and loves to spend time with his family.

Kartikay Khator is a Solutions Architect within Global Life Sciences at AWS, where he dedicates his efforts to developing innovative and scalable solutions that cater to the evolving needs of customers. His expertise lies in harnessing the capabilities of AWS analytics services. Extending beyond his professional pursuits, he finds joy and fulfillment in the world of running and hiking. Having already completed two marathons, he is currently preparing for his next marathon challenge.

Navnit Shukla, an AWS Specialist Solution Architect specializing in Analytics, is passionate about helping clients uncover valuable insights from their data. Leveraging his expertise, he develops inventive solutions that empower businesses to make informed, data-driven decisions. Notably, Navnit is the accomplished author of the book “Data Wrangling on AWS,” showcasing his expertise in the field.

BDB-4354-awskamenKamen Sharlandjiev is a Sr. Big Data and ETL Solutions Architect, Amazon MWAA and AWS Glue ETL expert. He’s on a mission to make life easier for customers who are facing complex data integration and orchestration challenges. His secret weapon? Fully managed AWS services that can get the job done with minimal effort. Follow Kamen on LinkedIn to keep up to date with the latest Amazon MWAA and AWS Glue features and news!

Bosco Albuquerque is a Sr. Partner Solutions Architect at AWS and has over 20 years of experience working with database and analytics products from enterprise database vendors and cloud providers. He has helped technology companies design and implement data analytics solutions and products.

Tenant portability: Move tenants across tiers in a SaaS application

Post Syndicated from Aman Lal original https://aws.amazon.com/blogs/architecture/tenant-portability-move-tenants-across-tiers-in-a-saas-application/

In today’s fast-paced software as a service (SaaS) landscape, tenant portability is a critical capability for SaaS providers seeking to stay competitive. By enabling seamless movement between tiers, tenant portability allows businesses to adapt to changing needs. However, manual orchestration of portability requests can be a significant bottleneck, hindering scalability and requiring substantial resources. As tenant volumes and portability requests grow, this approach becomes increasingly unsustainable, making it essential to implement a more efficient solution.

This blog post delves into the significance of tenant portability and outlines the essential steps for its implementation, with a focus on seamless integration into the SaaS serverless reference architecture. The following diagram illustrates the tier change process, highlighting the roles of tenants and admins, as well as the impact on new and existing services in the architecture. The subsequent sections will provide a detailed walkthrough of the sequence of events shown in this diagram.

Incorporating tenant portability within a SaaS serverless reference architecture

Figure 1. Incorporating tenant portability within a SaaS serverless reference architecture

Why do we need tenant portability?

  • Flexibility: Tier upgrades or downgrades initiated by the tenant help align with evolving customer demand, preferences, budget, and business strategies. These tier changes generally alter the service contract between the tenant and the SaaS provider.
  • Quality of service: Generally initiated by the SaaS admin in response to a security breach or when the tenant is reaching service limits, these incidents might require tenant migration to maintain service level agreements (SLAs).

High-level portability flow

Tenant portability is generally achieved through a well-orchestrated process that ensures seamless tier transitions. This process comprises of the following steps:

High-level tenant portability flow

Figure 2. High-level tenant portability flow

  1. Port identity stores: Evaluate the need for migrating the tenant’s identity store to the target tier. In scenarios where the existing identity store is incompatible with the target tier, you’ll need to provision a new destination identity store and administrative users.
  2. Update tenant configuration: SaaS applications store tenant configuration details such as tenant identifier and tier that are required for operation.
  3. Resource management: Initiate deployment pipelines to provision resources in the target tier and update infrastructure-tenant mapping tables.
  4. Data migration: Migrate tenant data from the old tier to the newly provisioned target tier infrastructure.
  5. Cutover: Redirect tenant traffic to the new infrastructure, enabling zero-downtime utilization of updated resources.

Consideration walkthrough

We’ll now delve into each step of the portability workflow, highlighting key considerations for a successful implementation.

1. Port identity stores

The key consideration for porting identity is migrating user identities while maintaining a consistent end-user experience, without requiring password resets or changes to user IDs.

Create a new identity store and associated application client that the frontend can use; after that, we’ll need a mechanism to migrate users. In the reference architecture using Amazon Cognito, a silo refers to each tenant having its own user pool, while a pool refers to multiple tenants sharing a user pool through user groups.

To ensure a smooth migration process, it’s important to communicate with users and provide them with options to avoid password resets. One approach is to notify users to log in before a deadline to avoid password resets. Employ just-in-time migration, enabling password retention during login for uninterrupted user experience with existing passwords.

However, this requires waiting for all users to migrate, potentially leading to a prolonged migration window. As a complementary measure, after the deadline, the remaining users can be migrated by using bulk import, which enforces password resets. This ensures a consistent migration within a defined timeframe, albeit inconveniencing some users.

2. Update tenant configuration

SaaS providers rely on metadata stores to maintain all tenant-related configuration. Updates to tenant metadata should be completed carefully during the porting process. When you update the tenant configuration for the new tier, two key aspects must be considered:

  • Retain tenant IDs throughout the porting process to ensure smooth integration of tenant logging, metrics, and cost allocation post-migration, providing a continuous record of events.
  • Establish new API keys and a throttling mechanism tailored to the new tier to accommodate higher usage limits for the tenants.

To handle this, a new tenant portability service can be introduced in the SaaS reference architecture. This service assigns a different AWS API Gateway usage plan to the tenant based on the requested tier change, and orchestrates calls to other downstream services. Subsequently, the existing tenant management service will need an extension to handle tenant metadata updates (tier, user-pool-id, app-client-id) based on the incoming porting request.

3. Resource management

Successful portability hinges on two crucial aspects during infrastructure provisioning:

  • Ensure tenant isolation constructs are respected in the porting process through mechanisms to prevent cross-tenant access. Either role-based access control (RBAC) or attribute-based-access control (ABAC) can be used to ensure this. ABAC isolation is generally easier to manage during porting if the tenant identifier is preserved, as in the previous step.
  • Ensure instrumentation and metric collection are set up correctly in the new tier. Recreate identical metric filters to ensure monitoring visibility for SaaS operations.

To handle infrastructure provisioning and deprovisioning in the reference architecture, extend the tenant provisioning service:

  • Update the tenant-stack mapping table to record migrated tenant stack details.
  • Initiate infrastructure provisioning or destruction pipelines as needed (for example, to run destruction pipelines after the data migration and user cutover steps).

Finally, ensure new resources comply with required compliance standards by applying relevant security configurations and deploying a compliant version of the application.

By addressing these aspects, SaaS providers can ensure a seamless transition while maintaining tenant isolation and operational continuity.

4. Data migration

The data migration strategy is heavily influenced by architectural decisions such as the storage engine and isolation approach. Minimizing user downtime during migration requires a focus on accelerating the migration process, maintaining service availability, and setting up a replication channel for incremental updates. Additionally, it’s crucial to address schema changes made by tenants in a silo model to ensure data integrity and avoid data loss when transitioning to a pool model.

Extending the reference architecture, a new data porting service can be introduced to enable Amazon DynamoDB data migration between different tiers. DynamoDB partition migration can be accomplished through multiple approaches, including AWS Glue, custom scripts, or duplicating DynamoDB tables and bulk-deleting partitions. We recommend a hybrid approach to achieve zero-downtime migration. This solution applies only when the DynamoDB schema remains consistent across tiers. If the schema has changed, a custom solution is required for data migration.

5. Cutover

The cutover phase involves redirecting users to the new infrastructure, disabling continuous data replication, and ensuring that compliance requirements are met. This includes running tests or obtaining audits/certifications, especially when moving to high-sensitivity silos. After a successful cutover, cleanup activities are necessary, including removing temporary infrastructure and deleting historical tenant data from the previous tier. However, before deleting data, ensure that audit trails are preserved and compliant with regulatory requirements, and that data deletion aligns with organizational policies.

Conclusion

In conclusion, portability is a vital feature for multi-tenant SaaS. It allows tenants to move data and configurations between tiers effortlessly and can be incorporated in reference architecture as above. Key considerations include maintaining consistent identities, staying compliant, reducing downtime and automating the process.

How to use Amazon Q Developer to deploy a Serverless web application with AWS CDK

Post Syndicated from Riya Dani original https://aws.amazon.com/blogs/devops/how-to-use-amazon-q-developer-to-deploy-a-serverless-web-application-with-aws-cdk/

Did you know that Amazon Q Developer, a new type of Generative AI-powered (GenAI) assistant, can help developers and DevOps engineers accelerate Infrastructure as Code (IaC) development using the AWS Cloud Development Kit (CDK)?

IaC is a practice where infrastructure components such as servers, networks, and cloud resources are defined and managed using code. Instead of manually configuring and deploying infrastructure, with IaC, the desired state of the infrastructure is specified in a machine-readable format, like YAML, JSON, or modern programming languages. This allows for consistent, repeatable, and scalable infrastructure management, as changes can be easily tracked, tested, and deployed across different environments. IaC reduces the risk of human errors, increases infrastructure transparency, and enables the application of DevOps principles, such as version control, testing, and automated deployment, to the infrastructure itself.

There are different IaC tools available to manage infrastructure on AWS. To manage infrastructure as code, one needs to understand the DSL (domain-specific language) of each IaC tool and/or construct interface and spend time defining infrastructure components using IaC tools. With the use of Amazon Q Developer, developers can minimize time spent on this undifferentiated task and focus on business problems. In this post, we will go over how Amazon Q Developer can help deploy a fully functional three-tier web application infrastructure on AWS using CDK. AWS CDK is an open-source software development framework to define cloud infrastructure in modern programming languages and provision it through AWS CloudFormation.

Amazon Q Developer is a generative artificial intelligence (AI)-powered conversational assistant that can help you understand, build, extend, and operate AWS applications. You can ask questions about AWS architecture, your AWS resources, best practices, documentation, support, and more. Amazon Q Developer is constantly updating its capabilities so your questions get the most contextually relevant and actionable answers.

In the following sections, we will take a real-world three-tier web application that uses serverless architecture and showcase how you can accelerate AWS CDK code development using Amazon Q Developer as an AI coding companion and thus improve developer productivity.

Prerequisites

To begin using Amazon Q Developer, the following are required:

Application Overview

You are a DevOps engineer at a software company and have been tasked with building and launching a new customer-facing web application using a serverless architecture. It will have three tiers, as shown below, consisting of the presentation layer, application layer, and data layer. You have decided to utilize Amazon Q Developer to deploy the application components using AWS CDK.

Three-Tier Web Application Architecture Overview

Figure 1 – Serverless Application Architecture

Accelerating application deployment using Amazon Q Developer as an AI coding companion

Let’s dive into how Amazon Q Developer can be used as an expert companion to accelerate the deployment of the above serverless application resources using AWS CDK.

1. Deploy Presentation Layer Resources

Creating a secured Amazon S3 bucket to host static assets and front it using Amazon CloudFront

When building modern serverless web applications that host large static content, a key architecture consideration is how to efficiently and securely serve static assets such as images, CSS, and JavaScript files. Simply serving these from your application servers can lead to scaling and performance bottlenecks with increased resource utilization (e.g., CPU, I/O, network) on servers. This is where leveraging AWS services like Amazon Simple Storage Service (Amazon S3) and Amazon CloudFront can be a game-changer. By hosting your static content in a secured S3 bucket, you unlock several powerful benefits. First and foremost, you get robust security controls through S3 bucket policies and CloudFront Origin Access Control (OAC) to ensure only authorized access. This is critical for protecting your assets. Secondly, you take load off your application servers by having CloudFront directly serve static assets from its globally distributed edge locations. This improves application performance and reduces operational costs. AWS CDK helps to simplify the infrastructure provisioning by allowing developers to define S3 bucket and CloudFront resource configurations in a modern programming language using CDK constructs that enhance security and include best practices recommendations.

In this application architecture, we will use Amazon Q Developer to develop AWS CDK code to provision presentation layer resources, which include a secured S3 bucket with public access disabled and an Origin Access Control (OAC) that is used to grant CloudFront access to the S3 bucket to securely serve the static assets of the application.

Prompt: Create a cdk stack with python that creates an s3 bucket for cloudfront/s3 static asset, ensure it is secured by using Origin Access Control (OAC)

Figure 2 - Using Amazon Q to Generate python CDK code for the presentation layer resources

Using Amazon Q to Generate python CDK code for the presentation layer resources

Developers can customize these configurations using Amazon Q Developer based on your specific security requirements, such as implementing access controls through IAM policies or enabling bucket logging for audit trails. This approach ensures that the S3 bucket is configured securely, aligning with best practices for data protection and access management.

Lets look at an example of adding CloudTrail logging to the S3 bucket:

Prompt: Update the code to include cloudtrail logging to the S3 bucket created

Using Amazon Q Developer to add CloudTrail logging to the S3 bucket

Using Amazon Q Developer to add CloudTrail logging to the S3 bucket

2. Deploy Application Layer Resources

Provision AWS Lambda and Amazon API Gateway to serve end-user requests

Amazon Q Developer makes it easy to provision serverless application backend infrastructure such as AWS Lambda and Amazon API Gateway using AWS CDK. In the above architecture, you can deploy the Lambda function hosting application code, with just a few lines of CDK code along with Lambda configuration such as function name, runtime, handler, timeouts, and environment variables. This Lambda function is fronted using Amazon API Gateway to serve user requests. Anything from a simple micro-service to a complex serverless application can be defined through code in CDK using Amazon Q assistance and deployed repeatedly through CI/CD pipelines. This enables infrastructure automation and consistent governance for applications on AWS.

Prompt: Create a CDK stack that creates a AWS Lambda function that is invoked by Amazon API Gateway

Using Amazon Q Developer to generate CDK code to create an AWS Lambda function that is invoked by Amazon API Gateway

Using Amazon Q Developer to generate CDK code to create an AWS Lambda function that is invoked by Amazon API Gateway

3. Deploy Data Layer Resources

Provision Amazon DynamoDB tables to host application data

By leveraging Amazon Q Developer, we can generate CDK code to provision DynamoDB tables using CDK constructs that offer AWS default best practice recommendations. With Amazon Q Developer, using the CDK construct library, we can define DynamoDB table names, attributes, secondary indexes, encryption, and auto-scaling in just a few lines of CDK code in our programming language of choice. With CDK, this table definition is synthesized into an AWS CloudFormation template that is deployed as a stack to provision the DynamoDB table with all the desired settings. Any data layer resources can be defined this way as Infrastructure as Code (IAC) using Amazon Q Developer. Overall, Amazon Q Developer drastically simplifies deploying managed data backends on AWS through CDK while enforcing best practices around data security, access control, and scalability leveraging CDK constructs.

Prompt: Create a CDK stack of a DynamoDB table with 100 read capacity units and 100 write capacity units.

Using Amazon Q Developer to generate CDK code to create a DynamoDB with 100 read capacity units and 100 write capacity units

Using Amazon Q Developer to generate CDK code to create a DynamoDB with 100 read capacity units and 100 write capacity units

4. Monitoring the Application Components

Monitoring using Amazon CloudWatch

Once the application infrastructure stack has been provisioned, it’s important to setup observability to monitor key metrics, detect any issues proactively, and alert operational teams to troubleshoot and fix issues to minimize application downtime. To get started with observability, developers can leverage Amazon CloudWatch, a fully managed monitoring service. With the use of AWS CDK, it is easy to codify CloudWatch components such as dashboards, metrics, log groups, and alarms alongside the application infrastructure and deploy them in an automated and repeatable way leveraging the AWS CDK construct library. Developers can customize these metrics and alarms to meet their workload requirements. All the monitoring configuration gets deployed as part of the infrastructure stack.

Developers can use Amazon Q Developer to assist with setting up application monitoring in AWS using CloudWatch and CDK. With Q, you can describe the resources you want to monitor, such as EC2 instances, Lambda functions, and RDS databases. Q will then generate the necessary CDK code to provision the appropriate CloudWatch alarms, metrics, and dashboards to monitor the resources. By describing what you want to monitor in natural language, Q handles the underlying complexity of generating code.

Prompt: Create a CDK stack of a Cloudwatch event rule to stop web instance EC2 instance every day at 15:00 UTC

Using Amazon Q Developer to generate CDK code to create a CloudWatch event rule to stop an EC2 instance at 15:00 UTC

Using Amazon Q Developer to generate CDK code to create a CloudWatch event rule to stop an EC2 instance at 15:00 UTC

5. Automate CI/CD of the application

Build a CDK Pipeline for Continuous Integration(CI) and Continuous Deployment(CD) of the Infrastructure

As you iterate on your serverless application, you’ll want a smooth, automated way to reliably deploy infrastructure changes using a CI/CD pipeline. This is where implementing a CDK pipeline, an automated deployment pipeline, becomes useful. As we’ve seen, AWS Cloud Development Kit (CDK) allows you to define your entire multi-tier infrastructure as a reusable, version-controlled code construct. From S3 buckets to CloudFront, API Gateway, Lambda functions, databases and more, all of these can be deployed with IaC. This CI/CD pipeline streamlines the process of deploying both infrastructure and application code, integrating seamlessly with CI/CD best practices.

Here’s how you can leverage Amazon Q Developer to streamline the process of creating a CDK pipeline.

Prompt: Using python, create a CDK pipeline that deploys a three tier serverless application.

Using Amazon Q Developer to generate CDK pipeline using Python

Using Amazon Q Developer to generate CDK pipeline using Python

By leveraging Amazon Q Developer in your IDE for CDK pipeline creation, you can speed up adoption of CI/CD best practices, and receive real-time guidance on CDK deployment patterns, making the development process smoother. This CI/CD integration accelerates your CDK development experience, and allows you to focus on building robust and scalable AWS applications.

Conclusion

In this post, you have learned how developers can leverage Amazon Q Developer, a generative-AI powered assistant, as a true expert AI companion in assisting with accelerating Infrastructure As Code (IaC) Development using AWS CDK and seen how to deploy and manage AWS resources of a three-tier serverless application using AWS CDK. In addition to Infrastructure As Code, Amazon Q Developer can be leveraged to accelerate software development, minimize time spent on undifferentiated coding tasks, and help with troubleshooting, so that developers can focus on creative business problems to delight end-users. See the Amazon Q Developer documentation to get started.

Happy Building with Amazon Q Developer!

Riya Dani

Riya Dani is a Solutions Architect at Amazon Web Services (AWS), responsible for helping Enterprise customers on their journey in the cloud. She has a passion for learning and holds a Bachelor’s & Master’s degree in Computer Science from Virginia Tech. In her free time, she enjoys staying active and reading.

Jehu Gray

Jehu Gray is a Prototyping Architect at Amazon Web Services where he helps customers design solutions that fits their needs. He enjoys exploring what’s possible with IaC.

Janardhan Molumuri

Janardhan Molumuri is a Lead Technical Account Manager at AWS, come with over two decades of Engineering leadership experience, advising customers on their Cloud Adoption journey and emerging technologies. He has passion for speaking, writing, and enjoys exploring technology trends.

Deliver Amazon CloudWatch logs to Amazon OpenSearch Serverless

Post Syndicated from Balaji Mohan original https://aws.amazon.com/blogs/big-data/deliver-amazon-cloudwatch-logs-to-amazon-opensearch-serverless/

Amazon CloudWatch Logs collect, aggregate, and analyze logs from different systems in one place. CloudWatch provides subcriptions as a real-time feed of these logs to other services like Amazon Kinesis Data Streams, AWS Lambda, and Amazon OpenSearch Service. These subscriptions are a popular mechanism to enable custom processing and advanced analysis of log data to gain additional valuable insights. At the time of publishing this blog post, these subscription filters support delivering logs to Amazon OpenSearch Service provisioned clusters only. Customers are increasingly adopting Amazon OpenSearch Serverless as a cost-effective option for infrequent, intermittent and unpredictable workloads.

In this blog post, we will show how to use Amazon OpenSearch Ingestion to deliver CloudWatch logs to OpenSearch Serverless in near real-time. We outline a mechanism to connect a Lambda subscription filter with OpenSearch Ingestion and deliver logs to OpenSearch Serverless without explicitly needing a separate subscription filter for it.

Solution overview

The following diagram illustrates the solution architecture.

  1. CloudWatch Logs: Collects and stores logs from various AWS resources and applications. It serves as the source of log data in this solution.
  2. Subscription filter : A CloudWatch Logs subscription filter filters and routes specific log data from CloudWatch Logs to the next component in the pipeline.
  3. CloudWatch exporter Lambda function: This is a Lambda function that receives the filtered log data from the subscription filter. Its purpose is to transform and prepare the log data for ingestion into the OpenSearch Ingestion pipeline.
  4. OpenSearch Ingestion: This is a component of OpenSearch Service. The Ingestion pipeline is responsible for processing and enriching the log data received from the CloudWatch exporter Lambda function before storing it in the OpenSearch Serverless collection.
  5. OpenSearch Service: This is fully managed service that stores and indexes log data, making it searchable and available for analysis and visualization. OpenSearch Service offers two configurations: provisioned domains and serverless. In this setup, we use serverless, which is an auto-scaling configuration for OpenSearch Service.

Prerequisites

Deploy the solution

With the prerequisites in place, you can create and deploy the pieces of the solution.

Step 1: Create PipelineRole for ingestion

  • Open the AWS Management Console for AWS Identity and Access Management (IAM).
  • Choose Policies, and then choose Create policy.
  • Select JSON and paste the following policy into the editor:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Action": [
                "aoss:BatchGetCollection",
                "aoss:APIAccessAll"
            ],
            "Effect": "Allow",
            "Resource": "arn:aws:aoss:us-east-1:{accountId}:collection/{collectionId}"
        },
        {
            "Action": [
                "aoss:CreateSecurityPolicy",
                "aoss:GetSecurityPolicy",
                "aoss:UpdateSecurityPolicy"
            ],
            "Effect": "Allow",
            "Resource": "*",
            "Condition": {
                "StringEquals": {
                    "aoss:collection": "{collection}"
                }
            }
        }
    ]
}

// Replace {accountId}, {collectionId}, and {collection} with your own values
  • Choose Next, choose Next, and name your policy collection-pipeline-policy.
  • Choose Create policy.
  • Next, create a role and attach the policy to it. Choose Roles, and then choose Create role.
  • Select Custom trust policy and paste the following policy into the editor:
{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Effect":"Allow",
         "Principal":{
            "Service":"osis-pipelines.amazonaws.com"
         },
         "Action":"sts:AssumeRole"
      }
   ]
}
  • Choose Next, and then search for and select the collection-pipeline-policy you just created.
  • Choose Next and name the role PipelineRole.
  • Choose Create role.

Step 2: Configure the network and data policy for OpenSearch collection

  • In the OpenSearch Service console, navigate to the Serverless menu.
  • Create a VPC endpoint by following the instruction in Create an interface endpoint for OpenSearch Serverless.
  • Go to Security and choose Network policies.
  • Choose Create network policy.
  • Configure the following policy
[
  {
    "Rules": [
      {
        "Resource": [
          "collection/{collection name}"
        ],
        "ResourceType": "collection"
      }
    ],
    "AllowFromPublic": false,
    "SourceVPCEs": [
      "{VPC Enddpoint Id}"
    ]
  },
  {
    "Rules": [
      {
        "Resource": [
          "collection/{collection name}"
        ],
        "ResourceType": "dashboard"
      }
    ],
    "AllowFromPublic": true
  }
]
  • Go to Security and choose Data access policies.
  • Choose Create access policy.
  • Configure the following policy:
[
  {
    "Rules": [
      {
        "Resource": [
          "index/{collection name}/*"
        ],
        "Permission": [
          "aoss:CreateIndex",
          "aoss:UpdateIndex",
          "aoss:DescribeIndex",
          "aoss:ReadDocument",
          "aoss:WriteDocument"
        ],
        "ResourceType": "index"
      }
    ],
    "Principal": [
      "arn:aws:iam::{accountId}:role/PipelineRole",
      "arn:aws:iam::{accountId}:role/Admin"
    ],
    "Description": "Rule 1"
  }
]

Step 3: Create an OpenSearch Ingestion pipeline

  • Navigate to the OpenSearch Service.
  • Go to the Ingestion pipelines section.
  • Choose Create pipeline.
  • Define the pipeline configuration.
version: "2"
 cwlogs-ingestion-pipeline:

  source:

    http:

      path: /logs/ingest

  sink:

    - opensearch:

        # Provide an AWS OpenSearch Service domain endpoint

        hosts: ["https://{collectionId}.{region}.aoss.amazonaws.com"]

        index: "cwl-%{yyyy-MM-dd}"

        aws:

          # Provide a Role ARN with access to the domain. This role should have a trust relationship with osis-pipelines.amazonaws.com

          sts_role_arn: "arn:aws:iam::{accountId}:role/PipelineRole"

          # Provide the region of the domain.

          region: "{region}"

          serverless: true

          serverless_options:

            network_policy_name: "{Network policy name}"
 # To get the values for the placeholders: 
 # 1. {collectionId}: You can find the collection ID by navigating to the Amazon OpenSearch Serverless Collection in the AWS Management Console, and then clicking on the Collection. The collection ID is listed under the "Overview" section. 
 # 2. {region}: This is the AWS region where your Amazon OpenSearch Service domain is located. You can find this information in the AWS Management Console when you navigate to the domain. 
 # 3. {accountId}: This is your AWS account ID. You can find your account ID by clicking on your username in the top-right corner of the AWS Management Console and selecting "My Account" from the dropdown menu. 
 # 4. {Network policy name}: This is the name of the network policy you have configured for your Amazon OpenSearch Serverless Collection. If you haven't configured a network policy, you can leave this placeholder as is or remove it from the configuration.
 # After obtaining the necessary values, replace the placeholders in the configuration with the actual values.            

Step 4: Create a Lambda function

  • Create a Lambda layer for requests and sigv4 packages. Run the following commands in AWS Cloudshell.
mkdir lambda_layers
 cd lambda_layers
 mkdir python
 cd python
 pip install requests -t ./
 pip install requests_auth_aws_sigv4 -t ./
 cd ..
 zip -r python_modules.zip .


 aws lambda publish-layer-version --layer-name Data-requests --description "My Python layer" --zip-file fileb://python_modules.zip --compatible-runtimes python3.x
import base64
 import gzip
 import json
 import logging
 import json
 import jmespath
 import requests
 from datetime import datetime
 from requests_auth_aws_sigv4 import AWSSigV4
 import boto3


 LOGGER = logging.getLogger(__name__)
 LOGGER.setLevel(logging.INFO)


 def lambda_handler(event, context):

    """Extract the data from the event"""

    data = jmespath.search("awslogs.data", event)

    """Decompress the logs"""

    cwLogs = decompress_json_data(data)

    """Construct the payload to send to OpenSearch Ingestion"""

    payload = prepare_payload(cwLogs)

    print(payload)

    """Ingest the set of events to the pipeline"""    

    response = ingestData(payload)

    return {

        'statusCode': 200

    }
 def decompress_json_data(data):

    compressed_data = base64.b64decode(data)

    uncompressed_data = gzip.decompress(compressed_data)

    return json.loads(uncompressed_data)


 def prepare_payload(cwLogs):

    payload = []

    logEvents = cwLogs['logEvents']

    for logEvent in logEvents:

        request = {}

        request['id'] = logEvent['id']

        dt = datetime.fromtimestamp(logEvent['timestamp'] / 1000) 

        request['timestamp'] = dt.isoformat()

        request['message'] = logEvent['message'];

        request['owner'] = cwLogs['owner'];

        request['log_group'] = cwLogs['logGroup'];

        request['log_stream'] = cwLogs['logStream'];

        payload.append(request)

    return payload

 def ingestData(payload):

    ingestionEndpoint = '{OpenSearch Pipeline Endpoint}'

    endpoint = 'https://' + ingestionEndpoint

    headers = {'Content-Type': 'application/json', 'Accept':'application/json'}

    r = requests.request('POST', f'{endpoint}/logs/ingest', json=payload, auth=AWSSigV4('osis'), headers=headers)

    LOGGER.info('Response received: ' + r.text)

    return r
  • Replace {OpenSearch Pipeline Endpoint}’ with the endpoint of your OpenSearch Ingestion pipeline.
  • Attach the following inline policy in execution role.
{

    "Version": "2012-10-17",

    "Statement": [

        {

            "Sid": "PermitsWriteAccessToPipeline",

            "Effect": "Allow",

            "Action": "osis:Ingest",

            "Resource": "arn:aws:osis:{region}:{accountId}:pipeline/{OpenSearch Pipeline Name}"

        }

    ]
 }
  • Deploy the function.

Step 5: Set up a CloudWatch Logs subscription

  • Grant permission to a specific AWS service or AWS account to invoke the specified Lambda function. The following command grants permission to the CloudWatch Logs service to invoke the cloud-logs Lambda function for the specified log group. This is necessary because CloudWatch Logs cannot directly invoke a Lambda function without being granted permission. Run the following command in CloudShell to add permission.
aws lambda add-permission
 --function-name "{function name}"
 --statement-id "{function name}"
 --principal "logs.amazonaws.com"
 --action "lambda:InvokeFunction"
 --source-arn "arn:aws:logs:{region}:{accountId}:log-group:{log_group}:*"
 --source-account "{accountId}"
  • Create a subscription filter for a log group. The following command creates a subscription filter on the log group, which forwards all log events (because the filter pattern is an empty string) to the Lambda function. Run the following command in Cloudshell to create the subscription filter.
aws logs put-subscription-filter
 --log-group-name {log_group}
 --filter-name {filter name}
 --filter-pattern ""
 --destination-arn arn:aws:lambda:{region}:{accountId}:function:{function name}

Step 6: Testing and verification

  • Generate some logs in your CloudWatch log group. Run the following command in Cloudshell to create sample logs in log group.
aws logs put-log-events --log-group-name {log_group} --log-stream-name {stream_name} --log-events "[{\"timestamp\":{timestamp in millis} , \"message\": \"Simple Lambda Test\"}]"
  • Check the OpenSearch collection to ensure logs are indexed correctly.

Clean up

Remove the infrastructure for this solution when not in use to avoid incurring unnecessary costs.

Conclusion

You saw how to set up a pipeline to send CloudWatch logs to an OpenSearch Serverless collection within a VPC. This integration uses CloudWatch for log aggregation, Lambda for log processing, and OpenSearch Serverless for querying and visualization. You can use this solution to take advantage of the pay-as-you-go pricing model for OpenSearch Serverless to optimize operational costs for log analysis.

To further explore, you can:


About the Authors

Balaji Mohan is a senior modernization architect specializing in application and data modernization to the cloud. His business-first approach ensures seamless transitions, aligning technology with organizational goals. Using cloud-native architectures, he delivers scalable, agile, and cost-effective solutions, driving innovation and growth.

Souvik Bose is a Software Development Engineer working on Amazon OpenSearch Service.

Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

Strengthening data security in AWS Step Functions with a customer-managed AWS KMS key

Post Syndicated from Chris Munns original https://aws.amazon.com/blogs/compute/strengthening-data-security-in-aws-step-functions-with-a-customer-managed-aws-kms-key/

This post is written by Dhiraj Mahapatro, AWS Principal Specialist SA, Serverless.

AWS Step Functions provides enhanced security with a customer-managed AWS KMS key. This allows organizations to maintain complete control over the encryption keys used to protect their data in Step Functions, ensuring that only allowed principals (IAM role, user, or a group) have access to the sensitive information that is processed in a state machine. This post explores the details of this feature and the new console experience of executing Step Functions workflows when a customer-managed KMS key is used.

Step Functions is a serverless orchestration service that enables you to coordinate multiple AWS services, microservices, and third-party integrations into business-critical applications. Step Functions is widely used for orchestrating complex workflows, such as loan processing, fraud detection, risk management, and compliance processes. By breaking down these processes into a series of steps, Step Functions provides a clear overview and control of the entire workflow. This ensures that it executes each stage correctly and in the right order. One of the critical aspects of using Step Functions in regulated industries is the importance of security and data protection. Step Functions manages sensitive customer data, including PII and financial records, and require protection against unauthorized access and data breaches. Enabling a customer-managed KMS key further strengthens the data security in a state machine.

Using customer-managed AWS KMS keys

With this launch, Step Functions enable encryption of the state machine definition and execution details, including event history using customer-managed symmetric KMS keys. As part of this feature, you also have the option to encrypt Step Functions activities using customer-managed key.

This post uses a sample application to show the implementation details of this new feature. See user guide for a detailed explanation of this feature.

The sample application shows a basic stock trading example where the state machine buys or sells a stock if the price of the stock is above or below 50 and finally saves the transaction.

Example workflow

Example workflow

The Step Functions Cloudformation resource of the state machine has a new property EncryptionConfiguration as shown in the following:

StockTradingStateMachine:
  Type: AWS::StepFunctions::StateMachine
  Properties:
    StateMachineName: !FindInMap ['StateMachine', 'Name', 'Value']
    RoleArn: !GetAtt StockTradingStateMachineExecutionRole.Arn
    EncryptionConfiguration:
      KmsKeyId: !Ref StocksKmsKey
      KmsDataKeyReusePeriodSeconds: 100
      Type: CUSTOMER_MANAGED_KMS_KEY
    Definition: . . .

Within EncryptionConfiguration, you specify the KmsKeyId and the Type. This sample application uses a CUSTOMER_MANAGED_KMS_KEY key type. The Type is a required field and it will be AWS_OWNED_KEY if it is not a customer managed key. The state machine also allows to specify the KmsDataKeyReusePeriodSeconds property to a value between 60 and 900 seconds (default: 300), which signifies the maximum duration for which the state machine reuses the data keys. When the period expires, Step Functions will call GenerateDataKey API on AWS KMS. Therefore, besides kms:Decrypt, Step Functions needs access to kms:GenerateDataKey action.

The sample application also creates a customer-managed KMS key with a condition to force the stock trading state machine to only use the key.

Security controls

Within an AWS Organization setup, the best practices guidance is to have a dedicated security organizational unit responsible for managing and enforcing security standards, including ownership of KMS keys. The security account provides cross-account access for the key usage. You grant admin access only to the root of the security account, while external or member accounts can access it for various purposes like decryption, encryption, description, and data key generation. This can be done through an IAM Role, User, or Group in the member account. The standard approach for cross-account access involves combining KMS key policies in the security account and IAM policies to the identity that gives permission for the service in the member account.

Cross account access

Cross account access

For Step Functions, you can go a step further to restrict access to the caller’s role in the member account and provide a condition. The condition forces Step Functions service to only use the key. For example, with a security account (id: 1111111111) and a member account (id: 1234567890), the KMS key policy can use a kms:ViaService condition to restrict access to Step Functions state machines present in us-east-1 region only:

{
  "Sid": "Allow access to member account via Step Functions service",
  "Effect": "Allow",
  "Principal": {
    "AWS": "arn:aws:iam::1234567890:role/MemberAccountRole"
  },
  "Action": ["kms:Decrypt", "kms:GenerateDataKey"],
  "Resource": "*",
  "Condition": {
    "StringEquals": {
      "kms:ViaService": "states.us-east-1.amazonaws.com"
    }
  }
}

Constantly updating the key policy for every new Step Functions workflow in member accounts is cumbersome. Therefore, a combination of KMS key policy and IAM roles grants fine-grained and least-privilege access to key actions. For organizations that do not have a security account or security organizational unit, the member account owns the KMS key, as shown below. The key policy must be more restrictive to the Step Functions execution role and the Step Functions ARN that will use the key.

Member account ownership

Member account ownership

For example, a member account with an account id 1234567890 sets the Step Functions execution role sfn-execution-role as the Principal and restricts the key usage to a specific Step Functions ARN in the same account by using kms:EncryptionContext:aws:states:stateMachineArn condition as shown in the following:

{
  "Effect": "Allow",
  "Principal": {
    "AWS": "arn:aws:iam::1234567890:role/sfn-execution-role"
  },
  "Action": ["kms:Decrypt", "kms:GenerateDataKey"],
  "Resource": "*",
  "Condition": {
    "StringEquals": {
      "kms:EncryptionContext:aws:states:stateMachineArn": 
      "arn:aws:states:us-east-1:1234567890:stateMachine:MyStateMachine"
    }
  }
}

Testing

To setup the application in your AWS account, you need the following tools:

Clone the git repository. To build and deploy your application for the first time, run the following in your shell from the repository home directory:

sam build && sam deploy –guided

You can find the State Machine’s ARN in the output values displayed after deployment.

Once deployed, run the application using the AWS CLI. Run the following command after replacing the state machine ARN from the output of the deployment and the region where you have the state machine:

aws stepfunctions start-execution \
  --state-machine-arn <state-machine-arn> \
  --region <region>

You get a successful response in the CLI. You can also see a corresponding execution listed in the AWS Console as RUNNING:

Running workflow

Running workflow

However, opening the execution details will show an “Access Denied” error as expected:

Access denied error

Access denied error

You get the same error while visualizing the Step Functions definition or editing the state machine. The sample application restricts the decryption by the KMS key to only the Step Functions workflow’s execution role. Therefore, any other entity cannot decrypt the state machine’s workflow execution details and the state machine’s definition. This secures the exposure of information, including the payload passed to Step Functions or the payload passed in between state transitions to external entities. This new feature will securely allow personally identifiable information (PII), credit card information (PCI), and other similar sensitive information in Step Functions. Existing sensitive workloads are now unlocked for Step Functions, therefore easing, making them AWS cloud native.

You can integrate Amazon CloudWatch Logs with Step Functions for logging and monitoring capabilities. To send logs, you must provide access for log delivery to decrypt your logs. In your State Machine customer-managed key policy, you must grant kms:decrypt permission to the principal delivery.logs.amazonaws.com. Logging a workflow will not work without above grant. You encrypted data is sent to CloudWatch logs with the same or different customer managed KMS key. See CloudWatch logs documentation to learn how to set permissions on the KMS key for your log group.

Cleanup

To delete the sample application, use the latest version of the AWS SAM CLI and run:

sam delete

Conclusion

Customer-managed AWS KMS keys in Step Functions allows for access control sensitive data. KMS key policy and IAM identity policies determine who decrypts and access various aspects of the state machine, including the definition, execution details, and input/output payload transitions for each task. This is an essential feature for highly regulated industries like financial services. Apply these security guardrails using customer-managed AWS KMS keys at the organizational unit, business unit, or at the individual account level.

The sample application shows a way of using the customer managed KMS key in Step Functions resource in CloudFormation. The user guide provides additional details. Support for this feature is available in AWS CDK now while Terraform support will fast follow. Dive deeper into additional details from the Step Functions user guide.

For more serverless learning resources, visit Serverless Land.

Implementing multi-Region failover for Amazon API Gateway

Post Syndicated from Chris Munns original https://aws.amazon.com/blogs/compute/implementing-multi-region-failover-for-amazon-api-gateway/

This post is written by Marcos Ortiz, Principal AWS Solutions Architect and Khubyar Behramsha, Sr. AWS Solutions Architect.

In this post, you learn how organizations can evolve from a single-Region architecture API Gateway to a multi-Region one, using a reliable failover mechanism without dependencies on AWS control plane operations. An AWS Well-Architected best practice is to rely on the data plane and not the control plane during recovery. Failover controls should work with no dependencies on the primary Region. This pattern shows how to independently failover discrete services deployed behind a shared public API. Additionally, there is a walkthrough on how to deploy and test the proposed architecture, using our open-source code available on GitHub.

For many organizations, running services behind a Regional Amazon API Gateway endpoint aligned to AWS Well-Architected best practices, offers the right balance of resilience, simplicity, and affordability. However, depending on business criticality, regulatory requirements, or disaster recovery objectives, some organizations must deploy their APIs using a multi-Region architecture.

When dealing with business-critical applications, organizations often want full control over how and when to trigger a failover. A manually triggered failover allows for dependencies to be failed over in a specific order. Failover actions follow the chain of approvals needed, which helps prevent failing over to an unprepared replica or other flapping issues caused by intermittent disruptions. While the failover action or trigger has a human-in-the-loop component, the recommendation is for all subsequent actions to be automated as much as possible. This approach gives application owners control over the failover process, including the ability to trigger the failover in cases of intermittent issues.

Overview

One common approach for customers is to deploy a public Regional API with a custom domain name, providing more intuitive URLs for their users. The backend uses API mappings to connect multiple API stages to a custom domain. This approach allows service owners to deploy their services independently while sharing the same top-level API domain name. Here is a typical architecture that follows this pattern:

Regional endpoint with mapping

Regional endpoint with mapping

However, when trying to evolve this to a multi-Region architecture, organizations often struggle to fail over each service independently. If the preceding architecture is deployed in two Regions as-is, it becomes an all-or-nothing scenario, where organizations must either fail over all the services behind API Gateway or none.

Evolving to a multi-Region architecture

To enable each team to manage and failover their services independently, you can implement this new approach for a multi-Region architecture. Each service has its own subdomain, using API Gateway HTTP integrations to route the request to a given service. This allows the service APIs the flexibility to be independently failed over, or all at once, with the shared public API.

Multi-Region architecture

Multi-Region architecture

This is the request flow:

  1. Users access a specific service through the public shared API domain name using a URL suffix. For instance, to access service1, the end user would send a request to http://example.com/service1.
  2. Amazon Route 53 has the top-level domain, example.com, registered with a primary and a secondary failover record. It routes the request to the API Gateway external API endpoint in the primary Region (us-east-1).
  3. API Gateway uses an HTTP integration to forward the request to service1 at https://service1.example.com.
  4. Amazon Route 53, has the domain service1.example.com registered with a primary and a secondary failover record. It routes the request to the API Gateway service1 API Regional endpoint in the primary Region (us-east-1) when healthy and routes to the service1 API Regional endpoint in the secondary Region (us-west-2) when unhealthy.
  5. Represents the primary route for service1 configured in Amazon Route 53.
  6. Represents the secondary route for service1 configured in Amazon Route 53.

This solution requires deploying each service API in both the primary (us-east-1) and secondary (us-west-2) Regions. Both Regions use the same custom domain configuration. For the primary Region, primary DNS records for each service point to the Regional API Gateway distribution endpoint. In the secondary Region, secondary DNS records for each service point to the Regional API Gateway distribution endpoint in the secondary Region.

Route 53 records

Route 53 records

Active-passive manual failover

The example provided here enables a reliable failover mechanism that does not rely on the Amazon Route 53 control plane. It uses Amazon Route 53 Application Recovery Controller (Route 53 ARC), which provides a cluster with five Regional endpoints across five different AWS Regions. The failover process uses these endpoints, instead of manually editing Amazon Route 53 DNS records, which is a control plane operation. The routing controls in Route 53 ARC failover traffic from the primary Region to the secondary one.

Route 53 ARC routing controls

Route 53 ARC routing controls

Routing controls are on-off switches that enable you to redirect client traffic from one instance of your workload to another. Traffic re-routing is the result of setting associated DNS health checks as healthy or unhealthy.

Route 53 ARC toggles

Route 53 ARC toggles

Deploying the sample application

Pre-requisites

  1. A public domain (example.com) registered with Amazon Route 53. Follow the instructions here on how to register a domain and the instructions here to configure Amazon Route 53 as your DNS service.
  2. An AWS Certificate Manager certificate (*.example.com) for your domain name on both the primary and secondary Regions you plan to deploy the sample APIs.

Deploy the Amazon Route 53 ARC stack

Deploy the Amazon Route 53 ARC stack first, which creates a cluster and the routing controls that enable you to fail over the APIs.

Follow the detailed instructions here to deploy the Amazon Route 53 Application Recovery Controller (ARC) stack.

Deploy the Service1 API both in the primary and secondary Regions

This deploys an API Gateway Regional endpoint in each Region, which calls an AWS Lambda function to return the service name and the current AWS Region serving the request:

{"service": "service1", "region": "us-east-1"}

This is the code for the Lambda function:

import json
import os

def lambda_handler(event, context):
    return {
"statusCode": 200,
"body": json.dumps({
  "service": "service1",
  "region": os.environ['AWS_REGION']}),
}

Follow the detailed instructions here to deploy the service1 stack.

Deploy the Service2 API both in the primary and secondary Regions

This stack is similar to service1, but has a different domain name and returns service2 as the service name:

{"service": "service2", "region": "us-east-1"}

Follow the detailed instructions here to deploy the service2 stack.

Deploy the shared public API both in the primary and secondary Regions

This step configures HTTP endpoints so that when you call example.com/service1 or example.com/service2, it routes the request to the respective public DNS records you have set up for service1 and service2.

Follow the detailed instructions here to deploy the external API stack.

Failover tests

To test the deployed example, modify then run the provided test script:

  1. Update lines 3–5 in the test.sh file to reference the domain name you configured for your APIs.
  2. Provide execute permissions and run the script:
chmod +x ./test/sh
./test.sh

This script sends an HTTP request to each one of your three endpoints every 5 seconds. You can then use Amazon Route 53 ARC to fail over your services independently and see the responses served from different Regions.

Initially, all services are routing traffic to the us-east-1 Region:

Initial routing

Initial routing

With the following command, you update two routing controls for service1, setting the primary Region (us-east-1) health check state to off, and the secondary Region (us-west-2) health check state to on:

aws route53-recovery-cluster update-routing-control-states \
 --update-routing-control-state-entries \
 '[{"RoutingControlArn":"arn:aws:route53-recovery-control::111122223333:controlpanel/0123456bbbbbbb0123456bbbbbb0123456/routingcontrol/abcdefg1234567","RoutingControlState":"On"},
{"RoutingControlArn":"arn:aws:route53-recovery-control:: 111122223333:controlpanel/0123456bbbbbbb0123456bbbbbb0123456/routingcontrol/hijklmnop987654321","RoutingControlState":"Off"}]' \
 --region ap-southeast-2 \
 --endpoint-url https://abcd1234.route53-recovery-cluster.ap-southeast-2.amazonaws.com/v1

After a few seconds, the script terminal shows that service1 is now routing traffic to us-west-2, while the other services are still routing traffic to the us-east-1 Region.

Flipping service1 to backup Region

Flipping service1 to backup Region

To fail back service1 to the us-east-1 Region, run this command, now setting the service1 primary Region (us-east-1) health check state to on, and the secondary Region (us-west-2) health check state to off:

aws route53-recovery-cluster update-routing-control-states \
 --update-routing-control-state-entries \
 '[{"RoutingControlArn":"arn:aws:route53-recovery-control::111122223333:controlpanel/0123456bbbbbbb0123456bbbbbb0123456/routingcontrol/abcdefg1234567","RoutingControlState":"Off"},
{"RoutingControlArn":"arn:aws:route53-recovery-control:: 111122223333:controlpanel/0123456bbbbbbb0123456bbbbbb0123456/routingcontrol/hijklmnop987654321","RoutingControlState":"On"}]' \
 --region ap-southeast-2 \
 --endpoint-url https:// abcd1234.route53-recovery-cluster.ap-southeast-2.amazonaws.com/v1

After a few seconds, the script terminal shows that service1 is now routing traffic to the us-east-1 Region again, like the other services.

Routing recovery

Routing recovery

Cleaning up

After you are finished, follow the cleanup instructions on GitHub.

Conclusion

This solution helps put the control back in the hands of the teams managing critical workloads using API Gateway. By decoupling the frontend and backend, this solution gives organizations granular control over failover at the service level using Amazon Route 53 ARC to remove dependencies on control plane actions.

The pattern outlined also reduces the impact to consumers of the service as it allows you to use the same public API and top-level domain when moving from a single-Region to a multi-Region architecture.

For more resilience learning, visit AWS Architecture Blog – Resilience.

For more serverless learning, visit Serverless Land.

Refactoring to Serverless: From Application to Automation

Post Syndicated from Sindhu Pillai original https://aws.amazon.com/blogs/devops/refactoring-to-serverless-from-application-to-automation/

Serverless technologies not only minimize the time that builders spend managing infrastructure, they also help builders reduce the amount of application code they need to write. Replacing application code with fully managed cloud services improves both the operational characteristics and the maintainability of your applications thanks to a cleaner separation between business logic and application topology. This blog post shows you how.

Serverless isn’t a runtime; it’s an architecture

Since the launch of AWS Lambda in 2014, serverless has evolved to be more than just a cloud runtime. The ability to easily deploy and scale individual functions, coupled with per-millisecond billing, has led to the evolution of modern application architectures from monoliths towards loosely-coupled applications. Functions typically communicate through events, an interaction model that’s supported by a combination of serverless integration services, such as Amazon EventBridge and Amazon SNS, and Lambda’s asynchronous invocation model.

Modern distributed architectures with independent runtime elements (like Lambda functions or containers) have a distinct topology graph that represents which elements talk to others. In the diagram below, Amazon API Gateway, Lambda, EventBridge, and Amazon SQS interact to process an order in a typical Order Processing System. The topology has a major influence on the application’s runtime characteristics like latency, throughput, or resilience.

Serverless topology for an Order processing using AWS services

The role of cloud automation evolves

Cloud automation languages, commonly referred to as IaC (Infrastructure as Code), date back to 2011 with the launch of CloudFormation, which allowed users to declare a set of cloud resources in configuration files instead of issuing a series of API calls or CLI commands. Initial document-oriented automation languages like AWS CloudFormation and Terraform were soon complemented by frameworks like AWS Cloud Development Kit (CDK), CDK for Terraform, and Pulumi that introduced the ability to write cloud automation code in popular general-purpose languages like TypeScript, Python, or Java.

The role of cloud automation evolved alongside serverless application architectures. Because serverless technologies free builders from having to manage infrastructure, there really isn’t any “I” in serverless IaC anymore. Instead, serverless cloud automation primarily defines the application’s topology by connecting Lambda functions with event sources or targets, which can be other Lambda functions. This approach more closely resembles “AaC” – Architecture as Code – as the automation now defines the application’s architecture instead of provisioning infrastructure elements.

Improving serverless applications with automation code

By utilizing AWS serverless runtime features, automation code can frequently achieve the same functionality as your application code.

For example, the Lambda function below, written in TypeScript, sends a message to EventBridge:

export const handler = async (event: APIGatewayProxyEvent): Promise<APIGatewayProxyResult> => { 
    const result = // some logic
    const eventParam = new PutEventsCommand({
        Entries: [
            {
              Detail: JSON.stringify(result),
              DetailType: 'OrderCreated',
              EventBusName: process.env.EVENTBUS_NAME,
            }
          ]
    });
    await eventBridgeClient.send(eventParam);     return {
       statusCode: 200,
       body: JSON.stringify({ message: 'Order created', result }),
    };
};

You can achieve the same behavior using AWS Lambda Destinations, which instructs the Lambda runtime to publish an event after the completion of the function. You can configure Lambda destinations via below AWS CDK code, also written in TypeScript:

import {EventBridgeDestination} from "aws-cdk-lib/aws-lambda-destinations"

const createOrderLambda = new Function(this,'createOrderLambda', {
    functionName: `OrderService`,
    runtime: Runtime.NODEJS_20_X,
    code: Code.fromAsset('lambda-fns/send-message-using-destination'),
    handler: 'OrderService.handler',
 onSuccess: new EventBridgeDestination(eventBus)
});

With the AWS CDK, you can use the same programming languages for both application and automation code, allowing you to switch easily between the two.

The Lambda function can now focus on the business logic and doesn’t contain any reference to message sending or EventBridge. This separation of concerns is a best practice because changes to the business logic do not run the risk of breaking the architecture and vice versa.

export const handler = async (event: APIGatewayProxyEvent): Promise<APIGatewayProxyResult> => {
    const result = //some logic
    return {
        statusCode: 200,
        body: JSON.stringify({ message: 'Order created', result }),
     };
};

Instructing the serverless Lambda runtime to send the event has several advantages over hand-coding it inside the application code

  • It decouples application logic from topology. The message destination, consisting of the type of the service (e.g., EventBridge vs. another Lambda Function) and the destination’s ARN, define the application’s architecture (or topology). Embedding message sending in the application code mixes architecture with business logic. Handling the sending of the message in the runtime separates concerns and avoids having to touch the application code for a topology change.
  • It makes the composition explicit. If application code sends a message, it will likely read the destination from an environment variable, which is passed to the Lambda function. The name of the variable that is used for this purpose is buried in the application code, forcing you to rely on naming conventions. Defining all dependencies between service instances in automation code keeps them in a central location, and allows you to use code analysis and refactoring tools to reason about your architecture or make changes to it.
  • It avoids simple mistakes. Redundant code can lead to mistakes. For example, debugging a Lambda function that accidentally swapped day and month in the message’s date field took hours. Letting the runtime send messages avoids such errors.
  • Higher-level constructs simplify permission grants. Cloud automation libraries like CDK allow the creation of higher-level constructs, which can combine multiple resources and include necessary IAM permissions. You’ll write less code and avoid debugging cycles.
  • The runtime is more robust. Delegating message sending to the serverless runtime takes care of any required retries, ensuring the message to be sent and freeing builders from having to write extra code for such undifferentiated heavy lifting.

In summary, letting the managed service handle message passing makes your serverless application cleaner and more robust. We also like to say that it becomes “serverless-native” because it fully utilizes the native services available to the application.

Refactoring to serverless-native

Shifting code from application to automation is what we call “Refactoring to Serverless”. Refactoring is a term popularized by Martin Fowler in the late 90s to describe the restructuring of source code to alter its structure without changing its external behavior. Code refactoring can be as simple as extracting code into a separate method or more sophisticated like replacing conditional expressions with polymorphism.

Developers refactor their code to improve its readability and maintainability. A common approach in Test-Driven Development (TDD) is the so-called red-green-refactor cycle: write a test, which will be red because the functionality isn’t implemented, then write the code to make the test green, and finally refactor to counteract the growing entropy in the codebase.

Serverless refactoring takes inspiration from this concept but augments it to the context of serverless automation:

Serverless refactoring: A controlled technique for improving the design of serverless applications by replacing application code with equivalent automation code.

Let’s explore how serverless refactoring can enhance the design and runtime characteristics of a serverless application. The diagram below shows an AWS Step Functions workflow that performs a quality check through image recognition. An early implementation, shown on the left, would use an intermediate AWS Lambda function to call the Amazon Rekognition service. Thanks to the launch of Step Functions’ AWS SDK service integrations in 2021, you can refactor the workflow to directly call the Rekognition API. This refactored design, seen on the right, eliminates the Lambda function (assuming it didn’t perform any additional tasks), thereby reducing costs and runtime complexity.

Replacing Lambda with Service Integration in Step Function workflow

See the AWS CDK implementation for this refactoring, in TypeScript, on GitHub.

Refactoring Limitations

The initial example of replacing application code to send a message to SQS via Lambda Destinations reveals that refactoring from application to automation code isn’t 100% behavior-preserving.

First, Lambda Destinations are only triggered when the function is invoked asynchronously. For synchronous invocations, the function passes the results back to the caller, and does not invoke the destination. Second, the serverless runtime wraps the data returned from the function inside a message envelope, affecting how the message recipient parses the JSON object. The message data is placed inside the responsePayload field if sending to another Lambda function or the detail field if sending to an EventBridge destination. Last, Lambda Destinations sends a message after the function completes, whereas application code could send the message at any point during the execution.

Lambda Destination Execution

The last change in behavior will be transparent to well-architected asynchronous applications because they won’t depend on the timing of message delivery. If a Lambda function continues processing after sending a message (for example, to EventBridge), that code can’t assume that the message has been processed because delivery is asynchronous. A rare exception could be a loop waiting for the results from the downstream message processing, but such loops violate the principles of asynchronous integration and also waste compute resources (Amazon Step Functions is a great choice for asynchronous callbacks). If such behavior is required, it can be achieved by splitting the Lambda function into two parts.

Can Serverless Refactoring be Automated?

Traditional code refactoring like “Extract Method” is automated thanks to built-in support by many code editors. Serverless refactoring isn’t (yet) a fully automatic, 100%-equivalent code transformation because it translates application code into automation code (or vice versa). While AI-powered tools like Amazon Q Developer are getting us closer to that vision, we consider serverless refactoring primarily as a design technique for developers to better utilize the AWS runtime. Improved code design and runtime characteristics outweigh behavior differences, especially if your application includes automated tests.

Incorporating refactoring into your team structures

If a single team owns both the application and the automation code, refactoring takes place inside the team. However, serverless refactoring can cross team boundaries when separate teams develop business logic versus managing the underlying infrastructure, configuration, and deployment.

In such a model, AWS recommends that the development team be responsible for both the application code and the application-specific automation, such as the CDK code to configure Lambda Destinations, Step Functions workflows, or EventBridge routing. Splitting application and application-specific automation across teams would make the development team dependent on the platform team for each refactoring and introduce unnecessary friction.

If both teams use the same Infrastructure-as-Code (IaC) tool, say AWS CDK, the platform team can build reusable templates and constructs that encapsulate organizational requirements and guardrails, such as CDK constructs for S3 buckets with encryption enabled. Development teams can easily consume those resources across CDK stacks.

However, teams could use different IaC tools, for example, the infrastructure team prefers CloudFormation but the development team prefers AWS CDK. In this setup, development teams can build their automation on top of the CFN Modules provided by the infrastructure team. However, they won’t benefit from the same high-level programming abstractions as they do with CDK.

Collaboration in a split-team model

Continuous Refactoring

Just like traditional code refactoring, refactoring to serverless isn’t a one-time activity but an essential aspect of your software delivery. Because adding functionality increases your application’s complexity, regular refactoring can help keep complexity at bay and maintain your development velocity. Like with Continuous Delivery, you can improve your software delivery with Continuous Refactoring.

Teams who encounter difficulties with serverless refactoring might be lacking automated test coverage or cloud automation. So, refactoring can become a useful forcing function for teams to exercise software delivery hygiene, for example by implementing automated tests.

Getting Started

The refactoring samples discussed here are a subset of an extensive catalog of open source code examples, which you can find along with AWS CDK implementation examples at refactoringserverless.com. You can also dive deeper into how serverless refactoring can make your application architecture more loosely coupled in a separate blog post.

Use the examples to accelerate your own refactoring effort. Now Go Refactor!

Serverless ICYMI Q2 2024

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/serverless-icymi-q2-2024/

Welcome to the 26th edition of the AWS Serverless ICYMI (in case you missed it) quarterly recap. Every quarter, we share all the most recent product launches, feature enhancements, blog posts, webinars, live streams, and other interesting things that you might have missed!

In case you missed our last ICYMI, check out what happened last quarter here.

Calendar

Calendar

EDA Day – London 2024

The AWS Serverless DA team hosted the third Event-Driven Architecture (EDA) Day in London on May 14th. This event brought together prominent figures in the event-driven architecture community, AWS, and customer speakers.

EDA Day covered 13 sessions, 2 workshops, and a Q&A panel. David Boyne was the keynote speaker with a talk “Complexity is the Gotcha of Event-Driven Architecture”. There were AWS speakers including Matthew Meckes, Natasha Wright, Julian Wood, Gillian Amstrong, Josh Kahn, Veda Ramen, and Uma Ramadoss. There was also an impressive lineup of guest speakers, Daniele Frasca, David Anderson, Ryan Cormack, Sarah Hamilton, Sheen Brisals, Marcin Sodkiewicz, and Ben Ellerby.

Videos are available on YouTube

EDA Day London

EDA Day London

The future of Serverless

There has been a lot of talk about the future of serverless, with this year being the 10th anniversary of AWS Lambda. Eric Johnson addresses the topic in his ServerlessDays Milan keynote, “Now serverless is all grown up, what’s next”.

AWS Lambda

AWS launched support for the latest release of Ruby 3.3 is based on the new Amazon Linux 2023 runtime. The Ruby 3.3 runtime also provides access to the latest Ruby language features.

There is a new guide on how to retrieve data about Lambda functions that use a deprecated runtime.

Learn how to run code after returning a response from an AWS Lambda function. This post shows how to return a synchronous function response as soon as possible, yet also perform additional asynchronous work after you send the response. For example, you may store data in a database or send information to a logging system.

See how you can use the circuit-breaker pattern with Lambda extensions and Amazon DynamoDB. The circuit breaker pattern can help prevent cascading failures and improve overall system stability.

Circuit-breaker pattern

Circuit-breaker pattern

Lambda functions now scale up to 12X faster in the AWS GovCloud (US) Regions.

Powertools for AWS Lambda (Python) adds support for Agents for Amazon Bedrock.

The AWS SDK for JavaScript v2 enters maintenance mode on September 8, 2024 and reaches end-of-support on September 8, 2025.

Amazon CloudWatch Logs introduced Live Tail streaming CLI support.

Amazon ECS and AWS Fargate

You can now secure Amazon Elastic Container Service (Amazon ECS) workloads on AWS Fargate with customer managed keys (CMKs). Once you add your keys to AWS Key Management Service (AWS KMS), you can use these to encrypt the underlying ephemeral storage of an Amazon ECS task on AWS Fargate.

Windows containers on AWS Fargate now start faster, up to 42% for Windows Server 2022 Core. AWS has optimized the Windows Server AMIs, introduced EC2 fast launch with pre-provisioned snapshots, and reduced network latency.

Amazon ECS Service Connect is a networking capability to simplify service discovery, connectivity, and traffic observability for Amazon ECS. You can now proactively scale Amazon ECS services by using custom metrics.

ECS Connect custom metrics

ECS Service Connect custom metrics

AWS Step Functions

The AWS Step Functions TestState API allows you to test individual states independently and to integrate testing into your preferred development workflows. Learn how to accelerate workflow development to iterate faster.

Step Functions TestState API

Step Functions TestState API

Amazon EventBridge

Amazon EventBridge Pipes now supports event delivery through AWS PrivateLink. You can send events from an event source located in an Amazon Virtual Private Cloud (VPC) to a Pipes target without traversing the public internet.

Amazon Timestream for LiveAnalytics is now an EventBridge Pipes target. Timestream for LiveAnalytics is a fast, scalable, purpose-built time series database that makes it easy to store and analyze trillions of time series data points per day.

EventBridge has a new console dashboard which provides a centralized view of your resources, metrics, and quotas. The console has an improved Learn page and other console enhancements. When using the CloudFormation template export for Pipes, you can also generate the IAM role. There is a new Rules tab in the Event Bus detail page, and the monitoring tab in the Rule detail page now includes additional metrics.

EventBridge Scheduler has some new API request metrics for improved observability.

Generative AI

Amazon Bedrock is a fully managed Generative AI service that offers a choice of high-performing foundation models (FMs) from leading AI companies through a single API. Bedrock now supports new models, including Anthropic’s Claude 3.5, AI21 Labs’ Jamba-Instruct, Amazon Titan Text Premier.

The new Bedrock Converse API provides a consistent way to invoke Amazon Bedrock models and simplifies multi-turn conversations. There is also a JavaScript tutorial to walk you through sending requests to the Converse API using the Javascript SDK.

Amazon Q Developer is now generally available. Amazon Q Developer, part of the Amazon Q family, is a generative AI–powered assistant for software development. Amazon Q is available in the AWS Management Console and as an integrated development environment (IDE) extension for Visual Studio Code, Visual Studio, and JetBrains IDEs. Amazon Q Developer has knowledge of your AWS account resources and can help understand your costs.

Amazon Q list Lambda functions

Amazon Q list Lambda functions

You can use Amazon Q Developer to develop code features and transform code to upgrade Java applications. Amazon Q Developer also offers inline completions in the command line. For more information, see Reimagining software development with the Amazon Q Developer Agent.

Amazon Q code features

Amazon Q code features

Knowledge Bases for Amazon Bedrock now let you configure Guardrails, configure inference parameters, and offers observability logs.

Storage and data

Amazon S3 no longer charges for several HTTP error codes if initiated from outside your individual AWS account or AWS Organization.

You can automatically detect malware in new object uploads to S3 with Amazon GuardDuty.

Amazon Elastic File System (Amazon EFS) now support up to 1.5 GiB/s of throughput per client, a 3x increase over the previous limit of 500 MiB/s.

Discover architectural patterns for real-time analytics using Amazon Kinesis Data Streams in part 1 and part 2 and see how to optimize write throughput.

Amazon API Gateway

Amazon API Gateway now allows you to increase the integration timeout beyond the prior limit of 29 seconds. You can raise the integration timeout for Regional and private REST APIs, but this might require a reduction in your account-level throttle quota limit. This launch can help with workloads that require longer timeouts, such as Generative AI use cases with Large Language Models (LLMs).

You can also now use Amazon Verified Permissions to secure API Gateway REST APIs when using an Open ID connect (OIDC) compliant identity provider. You can now control access based on user attributes and group memberships, without writing code.

AWS AppSync

You can now invoke your AWS AppSync data sources in an event-driven manner. Previously, you could only invoke Lambda functions synchronously from AWS AppSync. AWS AppSync can now trigger Lambda functions in Event mode, asynchronously decoupling the API response from the Lambda invocation, which helps with long-running operations.

AWS AppSync now passes application request headers to Lambda custom authorizer functions. You can make authorization decisions based on the value of the authorization header, and the value of other headers that were sent with the request from the application client.

Learn best practices for AWS AppSync GraphQL APIs. See how to how to optimize the security, performance, coding standards, and deployment of your AWS AppSync API. AWS AppSync also has increase quotas, and new metrics

AWS Amplify

AWS Amplify Gen 2 is now generally available. This now provides a code-first developer experience for building full-stack apps using TypeScript. Amplify Gen 2 allows you to express app requirements like the data models, business logic, and authorization rules in TypeScript.

AWS Amplify Gen2

AWS Amplify Gen2

Amplify has a new experience for file storage. This post explores using Lambda to create serverless functions for Amplify using TypeScript. There are also new team environment workflows.

Serverless blog posts

April

May

June

Serverless container blog posts

April

May

June

Serverless Office Hours

Serverless Office Hours

Serverless Office Hours

April

May

June

Containers from the Couch

Containers from the Couch

Containers from the Couch

April

May

FooBar Serverless

April

February

June

Still looking for more?

The Serverless landing page has more information. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.

You can also follow the Serverless Developer Advocacy team on X (formerly Twitter) to see the latest news, follow conversations, and interact with the team.

And finally, visit the Serverless Land and Containers on AWS websites for all your serverless and serverless container needs.

Perform reindexing in Amazon OpenSearch Serverless using Amazon OpenSearch Ingestion

Post Syndicated from Utkarsh Agarwal original https://aws.amazon.com/blogs/big-data/perform-reindexing-in-amazon-opensearch-serverless-using-amazon-opensearch-ingestion/

Amazon OpenSearch Serverless is a serverless deployment option for Amazon OpenSearch Service that makes it straightforward to run search and analytics workloads without managing infrastructure. Customers using OpenSearch Serverless often need to copy documents between two indexes within the same collection or across different collections. This primarily arises from two scenarios:

  • Reindexing – You frequently need to update or modify index mapping due to evolving data needs or schema changes
  • Disaster recovery – Although OpenSearch Serverless data is inherently durable, you may want to copy data across AWS Regions for added redundancy and resiliency

Amazon OpenSearch Ingestion had recently introduced a feature supporting OpenSearch as a source. OpenSearch Ingestion, a fully managed, serverless data collector, facilitates real-time ingestion of log, metric, and trace data into OpenSearch Service domains and OpenSearch Serverless collections. We can leverage this feature to address these two scenarios, by reading the data from an OpenSearch Serverless Collection. This capability allows you to effortlessly copy data between indexes, making data management tasks more streamlined and eliminating the need for custom code.

In this post, we outline the steps to copy data between two indexes in the same OpenSearch Serverless collection using the new OpenSearch source feature of OpenSearch Ingestion. This is particularly useful for reindexing operations where you want to change your data schema. OpenSearch Serverless and OpenSearch Ingestion are both serverless services that enable you to seamlessly handle your data workflows, providing optimal performance and scalability.

Solution overview

The following diagram shows the flow of copying documents from the source index to the destination index using an OpenSearch Ingestion pipeline.

Implementing the solution consists of the following steps:

  1. Create an AWS Identity and Access Management (IAM) role to use as an OpenSearch Ingestion pipeline role.
  2. Update the data access policy attached to the OpenSearch Serverless collection.
  3. Create an OpenSearch Ingestion pipeline that simply copies data from one index to another, or you can even create an index template using the OpenSearch Ingestion pipeline to define explicit mapping, and then copy the data from the source index to the destination index with the defined mapping applied.

Prerequisites

To get started, you must have an active OpenSearch Serverless collection with an index that you want to reindex (copy). Refer to Creating collections to learn more about creating a collection.

When the collection is ready, note the following details:

  • The endpoint of the OpenSearch Serverless collection
  • The name of the index from which the documents need to be copied
  • If the collection is defined as a VPC collection, note down the name of the network policy attached to the collection

You use these details in the ingestion pipeline configuration.

Create an IAM role to use as a pipeline role

An OpenSearch Ingestion pipeline needs certain permissions to pull data from the source and write to its sink. For this walkthrough, both the source and sink are the same, but if the source and sink collections are different, modify the policy accordingly.

Complete the following steps:

  1. Create an IAM policy (opensearch-ingestion-pipeline-policy) that provides permission to read and send data to the OpenSearch Serverless collection. The following is a sample policy with least privileges (modify {account-id}, {region}, {collection-id} and {collection-name} accordingly):
    {
        "Version": "2012-10-17",
        "Statement": [{
                "Action": [
                    "aoss:BatchGetCollection",
                    "aoss:APIAccessAll"
                ],
                "Effect": "Allow",
                "Resource": "arn:aws:aoss:{region}:{account-id}:collection/{collection-id}"
            },
            {
                "Action": [
                    "aoss:CreateSecurityPolicy",
                    "aoss:GetSecurityPolicy",
                    "aoss:UpdateSecurityPolicy"
                ],
                "Effect": "Allow",
                "Resource": "*",
                "Condition": {
                    "StringEquals": {
                        "aoss:collection": "{collection-name}"
                    }
                }
            }
        ]
    }

  2. Create an IAM role (opensearch-ingestion-pipeline-role) that the OpenSearch Ingestion pipeline will assume. While creating the role, use the policy you created (opensearch-ingestion-pipeline-policy). The role should have the following trust relationship (modify {account-id} and {region} accordingly):
    {
        "Version": "2012-10-17",
        "Statement": [{
            "Effect": "Allow",
            "Principal": {
                "Service": "osis-pipelines.amazonaws.com"
            },
            "Action": "sts:AssumeRole",
            "Condition": {
                "StringEquals": {
                    "aws:SourceAccount": "{account-id}"
                },
                "ArnLike": {
                    "aws:SourceArn": "arn:aws:osis:{region}:{account-id}:pipeline/*"
                }
            }
        }]
    }

  3. Record the ARN of the newly created IAM role (arn:aws:iam::111122223333:role/opensearch-ingestion-pipeline-role).

Update the data access policy attached to the OpenSearch Serverless collection

After you create the IAM role, you need to update the data access policy attached to the OpenSearch Serverless collection. Data access policies control access to the OpenSearch operations that OpenSearch Serverless supports, such as PUT <index> or GET _cat/indices. To perform the update, complete the following steps:

  1. On the OpenSearch Service console, under Serverless in the navigation pane, choose Collections.
  2. From the list of the collections, choose your OpenSearch Serverless collection.
  3. On the Overview tab, in the Data access section, choose the associated policy.
  4. Choose Edit.
  5. Edit the policy in the JSON editor to add the following JSON rule block in the existing JSON (modify {account-id} and {collection-name} accordingly):
    {
        "Rules": [{
            "Resource": [
                "index/{collection-name}/*"
            ],
            "Permission": [
                "aoss:CreateIndex",
                "aoss:UpdateIndex",
                "aoss:DescribeIndex",
                "aoss:ReadDocument",
                "aoss:WriteDocument"
            ],
            "ResourceType": "index"
        }],
        "Principal": [
            "arn:aws:iam::{account-id}:role/opensearch-ingestion-pipeline-role"
        ],
        "Description": "Provide access to OpenSearch Ingestion Pipeline Role"
    }

You can also use the Visual Editor method to choose Add another rule and add the preceding permissions for arn:aws:iam::{account-id}:role/opensearch-ingestion-pipeline-role.

  1. Choose Save.

Now you have successfully allowed the OpenSearch Ingestion role to perform OpenSearch operations against the OpenSearch Serverless collection.

Create and configure the OpenSearch Ingestion pipeline to copy the data from one index to another

Complete the following steps:

  1. On the OpenSearch Service console, choose Pipelines under Ingestion in the navigation pane.
  2. Choose Create a pipeline.
  3. In Choose Blueprint, select OpenSearchDataMigrationPipeline.
  4. For Pipeline name, enter a name (for example, sample-ingestion-pipeline).
  5. For Pipeline capacity, you can define the minimum and maximum capacity to scale up the resources. For this walkthrough, you can use the default value of 2 Ingestion OCUs for Min capacity and 4 Ingestion OCUs for Max capacity. However, you can even choose different values as OpenSearch Ingestion automatically scales your pipeline capacity according to your estimated workload, based on the minimum and maximum Ingestion OpenSearch Compute Units (Ingestion OCUs) that you specify.
  6. Update the following information for the source:
    1. Uncomment hosts and specify the endpoint of the existing OpenSearch Serverless collection that was copied as part of prerequisites.
    2. Uncomment include and index_name_regex, and specify the name of the index that will act as the source (in this demo, we’re using logs-2024.03.01).
    3. Uncomment region under aws and specify the AWS Region where your OpenSearch Serverless collection is (for example, us-east-1).
    4. Uncomment sts_role_arn under aws and specify the role that has permission to read data from the OpenSearch Serverless collection (for example, arn:aws:iam::111122223333:role/opensearch-ingestion-pipeline-role). This is the same role that was added in the data access policy of the collection.
    5. Update the serverless flag to true.
    6. If the OpenSearch Serverless collection has VPC access, uncomment serverless_options and network_policy_name and specify the name of the network policy used for the collection.
    7. Uncomment scheduling, interval, index_read_count, and start_time and modify these parameters accordingly.
      Using these parameters makes sure the OpenSearch Ingestion pipeline processes the indexes multiple times (to pick up new documents).
      Note – If the collection specified in the sink is of the Time series or Vector search type, you can keep the scheduling, interval, index_read_count, and start_time parameters commented.
  1. Update the following information for the sink:
    1. Uncomment hosts and specify the endpoint of the existing OpenSearch Serverless collection.
    2. Uncomment sts_role_arn under aws and specify the role that has permission to write data into the OpenSearch Serverless collection (for example, arn:aws:iam::111122223333:role/opensearch-ingestion-pipeline-role). This is the same role that was added in the data access policy of the collection.
    3. Update the serverless flag to true.
    4. If the OpenSearch Serverless collection has VPC access, uncomment serverless_options and network_policy_name and specify the name of the network policy used for the collection.
    5. Update the value for index and provide the index name to which you want to transfer the documents (for example, new-logs-2024.03.01).
    6. For document_id, you can get the ID from the document metadata in the source and use the same in the target.
      However, it is important to note that custom document IDs are only supported for the Search type of collection. If your collection is of the Time Series or Vector Search type, you should comment out the document_id line.
    7. (Optional) The values for bucket, region and sts_role_arn keys within the dlq section can be modified to capture any failed requests in an S3 bucket.
      Note – Additional permission to opensearch-ingestion-pipeline-role needs to be given, if configuring DLQ. Please refer Writing to a dead-letter queue, for the changes required.
      For this walkthrough, you will not set up a DLQ. You can remove the entire dlq block.
  1. Now click on Validate pipeline to validate the pipeline configuration.
  2. For Network settings, choose your preferred setting:
    1. Choose VPC access and select your VPC, subnet, and security group to set up the access privately. Choose this option if the OpenSearch Serverless collection has VPC access. AWS recommends using a VPC endpoint for all production workloads.
    2. Choose Public to use public access. For this walkthrough, we select Public because the collection is also accessible from public network.
  3. For Log Publishing Option, you can either create a new Amazon CloudWatch group or use an existing CloudWatch group to write the ingestion logs. This provides access to information about errors and warnings raised during the operation, which can help during troubleshooting. For this walkthrough, choose Create new group.
  4. Choose Next, and verify the details you specified for your pipeline settings.
  5. Choose Create pipeline.

It will take a couple of minutes to create the ingestion pipeline. After the pipeline is created, you will see the documents in the destination index, specified in the sink (for example, new-logs-2024.03.01). After all the documents are copied, you can validate the number of documents by using the count API.

When the process is complete, you have the option to stop or delete the pipeline. If you choose to keep the pipeline running, it will continue to copy new documents from the source index according to the defined schedule, if specified.

In this walkthrough, the endpoint defined in the hosts parameter under source and sink of the pipeline configuration belonged to the same collection which was of the Search type. If the collections are different, you need to modify the permissions for the IAM role (opensearch-ingestion-pipeline-role) to allow access to both collections. Additionally, make sure you update the data access policy for both the collections to grant access to the OpenSearch Ingestion pipeline.

Create an index template using the OpenSearch Ingestion pipeline to define mapping

In OpenSearch, you can define how documents and their fields are stored and indexed by creating a mapping. The mapping specifies the list of fields for a document. Every field in the document has a field type, which defines the type of data the field contains. OpenSearch Service dynamically maps data types in each incoming document if an explicit mapping is not defined. However, you can use the template_type parameter with the index-template value and template_content with JSON of the content of the index-template in the pipeline configuration to define explicit mapping rules. You also need to define the index_type parameter with the value as custom.

The following code shows an example of the sink portion of the pipeline and the usage of index_type, template_type, and template_content:

sink:
    - opensearch:
        # Provide an AWS OpenSearch Service domain endpoint
        hosts: [ "<<OpenSearch-Serverless-Collection-Endpoint>>" ]
        aws:
          # Provide a Role ARN with access to the domain. This role should have a trust relationship with osis-pipelines.amazonaws.com
          sts_role_arn: "arn:aws:iam::111122223333:role/opensearch-ingestion-pipeline-role"
          # Provide the region of the domain.
          region: "us-east-1"
          # Enable the 'serverless' flag if the sink is an Amazon OpenSearch Serverless collection
          serverless: true
          # serverless_options:
            # Specify a name here to create or update network policy for the serverless collection
            # network_policy_name: "network-policy-name"
        # This will make it so each document in the source cluster will be written to the same index in the destination cluster
        index: "new-logs-2024.03.01"
        index_type: custom
        template_type: index-template
        template_content: >
          {
            "template" : {
              "mappings" : {
                "properties" : {
                  "Data" : {
                    "type" : "text"
                  },
                  "EncodedColors" : {
                    "type" : "binary"
                  },
                  "Type" : {
                    "type" : "keyword"
                  },
                  "LargeDouble" : {
                    "type" : "double"
                  }          
                }
              }
            }
          }
        # This will make it so each document in the source cluster will be written with the same document_id in the destination cluster
        document_id: "${getMetadata(\"opensearch-document_id\")}"
        # Enable the 'distribution_version' setting if the AWS OpenSearch Service domain is of version Elasticsearch 6.x
        # distribution_version: "es6"
        # Enable and switch the 'enable_request_compression' flag if the default compression setting is changed in the domain. See https://docs.aws.amazon.com/opensearch-service/latest/developerguide/gzip.html
        # enable_request_compression: true/false
        # Enable the S3 DLQ to capture any failed requests in an S3 bucket
        # dlq:
          # s3:
            # Provide an S3 bucket
            # bucket: "<<your-dlq-bucket-name>>"
            # Provide a key path prefix for the failed requests
            # key_path_prefix: "<<logs/dlq>>"
            # Provide the region of the bucket.
            # region: "<<us-east-1>>"
            # Provide a Role ARN with access to the bucket. This role should have a trust relationship with osis-pipelines.amazonaws.com
            # sts_role_arn: "<<arn:aws:iam::111122223333:role/opensearch-ingestion-pipeline-role>>"

Or you can create the index first, with the mapping in the collection before you start the pipeline.

If you want to create a template using an OpenSearch Ingestion pipeline, you need to provide aoss:UpdateCollectionItems and aoss:DescribeCollectionItems permission for the collection in the data access policy for the pipeline role (opensearch-ingestion-pipeline-role). The updated JSON block for the rule would look like the following:

{
    "Rules": [
      {
        "Resource": [
          "collection/{collection-name}"
        ],
        "Permission": [
          "aoss:UpdateCollectionItems",
          "aoss:DescribeCollectionItems"
        ],
        "ResourceType": "collection"
      },
      {
        "Resource": [
          "index/{collection-name}/*"
        ],
        "Permission": [
          "aoss:CreateIndex",
          "aoss:UpdateIndex",
          "aoss:DescribeIndex",
          "aoss:ReadDocument",
          "aoss:WriteDocument"
        ],
        "ResourceType": "index"
      }
    ],
    "Principal": [
      "arn:aws:iam::{account-id}:role/opensearch-ingestion-pipeline-role"
    ],
    "Description": "Provide access to OpenSearch Ingestion Pipeline Role"
  }

Conclusion

In this post, we showed how to use an OpenSearch Ingestion pipeline to copy data from one index to another in an OpenSearch Serverless collection. OpenSearch Ingestion also allows you to perform transformation of data using various processors. AWS offers various resources for you to quickly start building pipelines using OpenSearch Ingestion. You can use various built-in pipeline integrations to quickly ingest data from Amazon DynamoDB, Amazon Managed Streaming for Apache Kafka (Amazon MSK), Amazon Security Lake, Fluent Bit, and many more. You can use the following OpenSearch Ingestion blueprints to build data pipelines with minimal configuration changes.


About the Authors

Utkarsh Agarwal is a Cloud Support Engineer in the Support Engineering team at Amazon Web Services. He specializes in Amazon OpenSearch Service. He provides guidance and technical assistance to customers thus enabling them to build scalable, highly available, and secure solutions in the AWS Cloud. In his free time, he enjoys watching movies, TV series, and of course, cricket. Lately, he has also been attempting to master the art of cooking in his free time – the taste buds are excited, but the kitchen might disagree.
Prashant Agrawal is a Sr. Search Specialist Solutions Architect with Amazon OpenSearch Service. He works closely with customers to help them migrate their workloads to the cloud and helps existing customers fine-tune their clusters to achieve better performance and save on cost. Before joining AWS, he helped various customers use OpenSearch and Elasticsearch for their search and log analytics use cases. When not working, you can find him traveling and exploring new places. In short, he likes doing Eat → Travel → Repeat.

Securing Amazon ECS workloads on AWS Fargate with customer managed keys

Post Syndicated from Maish Saidel-Keesing original https://aws.amazon.com/blogs/compute/securing-amazon-ecs-workloads-on-aws-fargate-with-customer-managed-keys/

As Amazon CTO Werner Vogels said, “Encryption is the tool we have to make sure that nobody else has access to your data. Amazon Web Services (AWS) built encryption into nearly all of its 165 cloud services. Make use of it. Dance like nobody is watching. Encrypt like everyone is.”

Security is the top priority at AWS, underpinning everything we do. With AWS Fargate, every Amazon Elastic Container Service (Amazon ECS) task is launched on to a new single use, single tenant unit of compute. The ephemeral storage for this compute is always encrypted, and the AWS Key Management Service (AWS KMS) encryption key used for this encryption is managed by AWS Fargate.

Today, AWS is announcing that you can bring your own customer managed keys (CMKs). Once added to AWS KMS, you can use these to encrypt the underlying ephemeral storage of an Amazon ECS task on AWS Fargate. With this new capability, customers operating in heavily regulated environments can now have more control and visibility into their task’s ephemeral storage encryption.

This post dives into AWS Fargate task ephemeral storage and shows how the new customer managed key (CMK) feature can be enabled and audited.

Overview

AWS Fargate is a serverless compute engine for containerized workloads running on Amazon ECS and Amazon Elastic Kubernetes Service (Amazon EKS). Each time a new piece of work is scheduled on to AWS Fargate, as an Amazon ECS task or an Amazon EKS Pod, this workload is placed on a single use, single-tenant instance of compute.

For Amazon ECS tasks, that unit of compute has 20GiBs of ephemeral storage attached. This can be increased up to 200GiB by specifying the ephemeralStorage parameter in your task definition. This ephemeral storage is bound to the lifecycle of the Amazon ECS task, and once the Amazon ECS task has stopped, along with the underlying compute, this ephemeral storage is deleted.

If you are using AWS Fargate platform version 1.4.0 or higher, this ephemeral storage volume is encrypted by default. It is encrypted using an AWS Key Management Service (KMS) key with the AES-256 encryption algorithm. The key, and its lifecycle, is owned by the AWS Fargate service. You can learn more about Fargate-managed ephemeral storage encryption in the AWS Fargate Security Whitepaper.

With today’s launch, as an alternative to the Fargate-managed encryption, you can choose to encrypt the ephemeral storage with customer managed keys (CMKs). This helps regulation-sensitive customers meet their internal security policies and regulatory requirements.

Customers can import their own existing keys into AWS KMS or create a new CMK to encrypt the ephemeral storage. CMKs used by AWS Fargate can be managed through the normal AWS KMS lifecycle actions such as being rotated, disabled, and deleted. See the Amazon ECS documentation for more details on managing the KMS key. Additionally, all access from AWS Fargate to the KMS key can be audited in AWS CloudTrail Logs.

In January 2024, AWS announced that additional Amazon Elastic Block Store (Amazon EBS) volumes can now be attached to Amazon ECS tasks running on AWS Fargate. These EBS volumes unlock additional use cases for AWS Fargate customers, using higher capacity and high-performance volumes for use in their tasks alongside the ephemeral storage. These additional EBS volumes are managed differently to the ephemeral storage, and these volumes can already be encrypted with customer managed KMS keys (CMKs).

AWS Fargate falls under the scope of the following compliance programs regarding AWS’s side of the shared responsibility model. The compliance programs covered by AWS Fargate include:

You can download third-party audit reports using AWS Artifact. For more information, see Downloading Reports in AWS Artifact. Many of these compliance programs require customers to encrypt their data at rest within their Amazon ECS on AWS Fargate resources.

Customers also have additional internal risk management policies for key handling, where they must generate their own keys, have backups for these keys off-cloud, and manage the lifecycle of these keys. Until today, these customers could not use AWS Fargate’s default encryption solution for the workloads subject to their internal security policies.

Enabling CMK for ephemeral storage on an Amazon ECS Cluster

Following today’s launch a single KMS key can now be attached to a new or existing Amazon ECS Cluster. Once a key has been attached, all new tasks launched on to AWS Fargate use this KMS key. If you have existing tasks running in the Amazon ECS cluster, they must be redeployed to use the new encryption key. If these tasks are part of an Amazon ECS service, passing the –force-new-deployment flag to an amazon ecs update-service command forces all tasks to be redeployed with the new KMS key (while respecting the minimumHealthyPercent of the service).

To attach a KMS key to a new or existing cluster, specify the KeyId to the new managedStorageConfiguration field:

aws ecs create-cluster \
  --cluster clusterName \
  --configuration '{"managedStorageConfiguration":{"fargateEphemeralStorageKmsKeyId":"arn:aws:kms:us-west-2:012345678901:key/a1b2c3d4-5678-90ab-cdef-EXAMPLE11111"}}'

Here is an example of the output of a DescribeClusters API request to an Amazon ECS cluster with a customer managed key:

aws ecs describe-clusters --clusters ecs-fargate-self-managed-key-cluster --region us-west-2 --include CONFIGURATIONS

Result of describe-clusters query

Aside from auditing CloudTrail Logs for encryption events, you can also verify that an ECS task is using the KMS key by using the DescribeTask API on an existing task:

{
    "tasks": [
        {
            ....
            "clusterArn": "arn:aws:ecs:us-west-2:1234567890:cluster/mycluster",
            "taskArn": "arn:aws:ecs:us-west-2:1234567890:task/11223342-1111-4fde-b6ca-273c5cfc00a1]",
            "fargateEphemeralStorage": {
                "sizeInGiB": 20,
                "kmsKeyId": "arn:aws:kms:us-west-2:1234567890:key/082222a1-1111-4fde-b6ca-273c5cfc00a1"
            }
        }
    ]
}

Enforcing encryption with customer managed keys

The new AWS Identity and Access Management (IAM) condition key ensures that your Amazon ECS clusters are created with a customer managed key. This can be applied as Service Control Policy in your AWS Organization or as part of your IAM permissions.

Here is an IAM policy example snippet that ensures a cluster can only be created when a specific AWS KMS key is used:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "ecs:CreateCluster"
      ],
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "ecs:fargate-ephemeral-storage-kms-key": "arn:aws:kms:us-east-1:123456789012:key/1234abcd-12ab-34cd-56ef-1234567890ab"
        }
      }
    }
  ]
}

Audit encryption events

Encryption events are logged in AWS CloudTrail. The following is an example of a CloudTrail event that includes the volume ID, cluster name, and AWS Account ID of the operation. You can find more details about the type of events that are logged in Managing AWS KMS keys for Fargate ephemeral storage.

{
    "eventVersion": "1.08",
    "userIdentity": {
        "type": "AWSService",
        "invokedBy": "ec2-frontend-api.amazonaws.com"
    },
    "eventTime": "2024-04-23T18:08:13Z",
    "eventSource": "kms.amazonaws.com",
    "eventName": "CreateGrant",
    "awsRegion": "us-west-2",
    "sourceIPAddress": "ec2-frontend-api.amazonaws.com",
    "userAgent": "ec2-frontend-api.amazonaws.com",
    "requestParameters": {
        "keyId": "arn:aws:kms:us-west-2:123456789012:key/9b52b885-3f4d-40af-9843-d6b24b735559",
        "granteePrincipal": "fargate.us-west-2.amazonaws.com",
        "operations": [
            "Decrypt"
        ],
        "constraints": {
            "encryptionContextSubset": {
                "aws:ecs:clusterAccount": "123456789012",
                "aws:ebs:id": "vol-01234567890abcdef",
                "aws:ecs:clusterName": "ecs-fargate-self-managed-key-cluster"
            }
        },
        "retiringPrincipal": "ec2.us-west-2.amazonaws.com"
    },
    "responseElements": {
        "grantId": "e3b0c44298fc1c149afbf4c8996fb92427ae41e4649b934ca495991b7852b855",
        "keyId": "arn:aws:kms:us-west-2:123456789012:key/9b52b885-3f4d-40af-9843-d6b24b735559"
    },
    "requestID": "be4d1a4e4730e0dceca51f87ee7454d5db76400d80e22bfbf3c4ca01e893b60c",
    "eventID": "bf36027c-86bd-40f2-a561-960cbe148c4c",
    "readOnly": false,
    "resources": [
        {
            "accountId": "AWS Internal",
            "type": "AWS::KMS::Key",
            "ARN": "arn:aws:kms:us-west-2:123456789012:key/9b52b885-3f4d-40af-9843-d6b24b735559"
        }
    ],
    "eventType": "AwsApiCall",
    "managementEvent": true,
    "recipientAccountId": "123456789012",
    "sharedEventID": "bf36027c-86bd-40f2-a561-960cbe148c4c",
    "eventCategory": "Management"
}

Conclusion

With the use of AWS KMS customer managed keys, you can now meet your security requirements for your data inside your Amazon ECS workloads running on AWS Fargate.

To learn more about compliance on your Amazon ECS workloads you can reference the FSI Services Spotlight: Amazon Elastic Container Service (ECS) with AWS Fargate blog post or the security overview of AWS Fargate whitepaper. To learn more about the use of customer managed keys in AWS Fargate, refer to the AWS documentation. This feature was requested by our customers on the AWS Containers roadmap.

Disrupting FlyingYeti’s campaign targeting Ukraine

Post Syndicated from Cloudforce One original https://blog.cloudflare.com/disrupting-flyingyeti-campaign-targeting-ukraine


Cloudforce One is publishing the results of our investigation and real-time effort to detect, deny, degrade, disrupt, and delay threat activity by the Russia-aligned threat actor FlyingYeti during their latest phishing campaign targeting Ukraine. At the onset of Russia’s invasion of Ukraine on February 24, 2022, Ukraine introduced a moratorium on evictions and termination of utility services for unpaid debt. The moratorium ended in January 2024, resulting in significant debt liability and increased financial stress for Ukrainian citizens. The FlyingYeti campaign capitalized on anxiety over the potential loss of access to housing and utilities by enticing targets to open malicious files via debt-themed lures. If opened, the files would result in infection with the PowerShell malware known as COOKBOX, allowing FlyingYeti to support follow-on objectives, such as installation of additional payloads and control over the victim’s system.

Since April 26, 2024, Cloudforce One has taken measures to prevent FlyingYeti from launching their phishing campaign – a campaign involving the use of Cloudflare Workers and GitHub, as well as exploitation of the WinRAR vulnerability CVE-2023-38831. Our countermeasures included internal actions, such as detections and code takedowns, as well as external collaboration with third parties to remove the actor’s cloud-hosted malware. Our effectiveness against this actor prolonged their operational timeline from days to weeks. For example, in a single instance, FlyingYeti spent almost eight hours debugging their code as a result of our mitigations. By employing proactive defense measures, we successfully stopped this determined threat actor from achieving their objectives.

Executive Summary

  • On April 18, 2024, Cloudforce One detected the Russia-aligned threat actor FlyingYeti preparing to launch a phishing espionage campaign targeting individuals in Ukraine.
  • We discovered the actor used similar tactics, techniques, and procedures (TTPs) as those detailed in Ukranian CERT’s article on UAC-0149, a threat group that has primarily targeted Ukrainian defense entities with COOKBOX malware since at least the fall of 2023.
  • From mid-April to mid-May, we observed FlyingYeti conduct reconnaissance activity, create lure content for use in their phishing campaign, and develop various iterations of their malware. We assessed that the threat actor intended to launch their campaign in early May, likely following Orthodox Easter.
  • After several weeks of monitoring actor reconnaissance and weaponization activity (Cyber Kill Chain Stages 1 and 2), we successfully disrupted FlyingYeti’s operation moments after the final COOKBOX payload was built.
  • The payload included an exploit for the WinRAR vulnerability CVE-2023-38831, which FlyingYeti will likely continue to use in their phishing campaigns to infect targets with malware.
  • We offer steps users can take to defend themselves against FlyingYeti phishing operations, and also provide recommendations, detections, and indicators of compromise.

Who is FlyingYeti?

FlyingYeti is the cryptonym given by Cloudforce One to the threat group behind this phishing campaign, which overlaps with UAC-0149 activity tracked by CERT-UA in February and April 2024. The threat actor uses dynamic DNS (DDNS) for their infrastructure and leverages cloud-based platforms for hosting malicious content and for malware command and control (C2). Our investigation of FlyingYeti TTPs suggests this is likely a Russia-aligned threat group. The actor appears to primarily focus on targeting Ukrainian military entities. Additionally, we observed Russian-language comments in FlyingYeti’s code, and the actor’s operational hours falling within the UTC+3 time zone.

Campaign background

In the days leading up to the start of the campaign, Cloudforce One observed FlyingYeti conducting reconnaissance on payment processes for Ukrainian communal housing and utility services:

  • April 22, 2024 – research into changes made in 2016 that introduced the use of QR codes in payment notices
  • April 22, 2024 – research on current developments concerning housing and utility debt in Ukraine
  • April 25, 2024 – research on the legal basis for restructuring housing debt in Ukraine as well as debt involving utilities, such as gas and electricity

Cloudforce One judges that the observed reconnaissance is likely due to the Ukrainian government’s payment moratorium introduced at the start of the full-fledged invasion in February 2022. Under this moratorium, outstanding debt would not lead to evictions or termination of provision of utility services. However, on January 9, 2024, the government lifted this ban, resulting in increased pressure on Ukrainian citizens with outstanding debt. FlyingYeti sought to capitalize on that pressure, leveraging debt restructuring and payment-related lures in an attempt to increase their chances of successfully targeting Ukrainian individuals.

Analysis of the Komunalka-themed phishing site

The disrupted phishing campaign would have directed FlyingYeti targets to an actor-controlled GitHub page at hxxps[:]//komunalka[.]github[.]io, which is a spoofed version of the Kyiv Komunalka communal housing site https://www.komunalka.ua. Komunalka functions as a payment processor for residents in the Kyiv region and allows for payment of utilities, such as gas, electricity, telephone, and Internet. Additionally, users can pay other fees and fines, and even donate to Ukraine’s defense forces.

Based on past FlyingYeti operations, targets may be directed to the actor’s Github page via a link in a phishing email or an encrypted Signal message. If a target accesses the spoofed Komunalka platform at hxxps[:]//komunalka[.]github[.]io, the page displays a large green button with a prompt to download the document “Рахунок.docx” (“Invoice.docx”), as shown in Figure 1. This button masquerades as a link to an overdue payment invoice but actually results in the download of the malicious archive “Заборгованість по ЖКП.rar” (“Debt for housing and utility services.rar”).

Figure 1: Prompt to download malicious archive “Заборгованість по ЖКП.rar”

A series of steps must take place for the download to successfully occur:

  • The target clicks the green button on the actor’s GitHub page hxxps[:]//komunalka.github[.]io
  • The target’s device sends an HTTP POST request to the Cloudflare Worker worker-polished-union-f396[.]vqu89698[.]workers[.]dev with the HTTP request body set to “user=Iahhdr”
  • The Cloudflare Worker processes the request and evaluates the HTTP request body
  • If the request conditions are met, the Worker fetches the RAR file from hxxps[:]//raw[.]githubusercontent[.]com/kudoc8989/project/main/Заборгованість по ЖКП.rar, which is then downloaded on the target’s device

Cloudforce One identified the infrastructure responsible for facilitating the download of the malicious RAR file and remediated the actor-associated Worker, preventing FlyingYeti from delivering its malicious tooling. In an effort to circumvent Cloudforce One’s mitigation measures, FlyingYeti later changed their malware delivery method. Instead of the Workers domain fetching the malicious RAR file, it was loaded directly from GitHub.

Analysis of the malicious RAR file

During remediation, Cloudforce One recovered the RAR file “Заборгованість по ЖКП.rar” and performed analysis of the malicious payload. The downloaded RAR archive contains multiple files, including a file with a name that contains the unicode character “U+201F”. This character appears as whitespace on Windows devices and can be used to “hide” file extensions by adding excessive whitespace between the filename and the file extension. As highlighted in blue in Figure 2, this cleverly named file within the RAR archive appears to be a PDF document but is actually a malicious CMD file (“Рахунок на оплату.pdf[unicode character U+201F].cmd”).

Figure 2: Files contained in the malicious RAR archive “Заборгованість по ЖКП.rar” (“Housing Debt.rar”)

FlyingYeti included a benign PDF in the archive with the same name as the CMD file but without the unicode character, “Рахунок на оплату.pdf” (“Invoice for payment.pdf”). Additionally, the directory name for the archive once decompressed also contained the name “Рахунок на оплату.pdf”. This overlap in names of the benign PDF and the directory allows the actor to exploit the WinRAR vulnerability CVE-2023-38831. More specifically, when an archive includes a benign file with the same name as the directory, the entire contents of the directory are opened by the WinRAR application, resulting in the execution of the malicious CMD. In other words, when the target believes they are opening the benign PDF “Рахунок на оплату.pdf”, the malicious CMD file is executed.

The CMD file contains the FlyingYeti PowerShell malware known as COOKBOX. The malware is designed to persist on a host, serving as a foothold in the infected device. Once installed, this variant of COOKBOX will make requests to the DDNS domain postdock[.]serveftp[.]com for C2, awaiting PowerShell cmdlets that the malware will subsequently run.

Alongside COOKBOX, several decoy documents are opened, which contain hidden tracking links using the Canary Tokens service. The first document, shown in Figure 3 below, poses as an agreement under which debt for housing and utility services will be restructured.

Figure 3: Decoy document Реструктуризація боргу за житлово комунальні послуги.docx

The second document (Figure 4) is a user agreement outlining the terms and conditions for the usage of the payment platform komunalka[.]ua.

Figure 4: Decoy document Угода користувача.docx (User Agreement.docx)

The use of relevant decoy documents as part of the phishing and delivery activity are likely an effort by FlyingYeti operators to increase the appearance of legitimacy of their activities.

The phishing theme we identified in this campaign is likely one of many themes leveraged by this actor in a larger operation to target Ukrainian entities, in particular their defense forces. In fact, the threat activity we detailed in this blog uses many of the same techniques outlined in a recent FlyingYeti campaign disclosed by CERT-UA in mid-April 2024, where the actor leveraged United Nations-themed lures involving Peace Support Operations to target Ukraine’s military. Due to Cloudforce One’s defensive actions covered in the next section, this latest FlyingYeti campaign was prevented as of the time of publication.

Mitigating FlyingYeti activity

Cloudforce One mitigated FlyingYeti’s campaign through a series of actions. Each action was taken to increase the actor’s cost of continuing their operations. When assessing which action to take and why, we carefully weighed the pros and cons in order to provide an effective active defense strategy against this actor. Our general goal was to increase the amount of time the threat actor spent trying to develop and weaponize their campaign.

We were able to successfully extend the timeline of the threat actor’s operations from hours to weeks. At each interdiction point, we assessed the impact of our mitigation to ensure the actor would spend more time attempting to launch their campaign. Our mitigation measures disrupted the actor’s activity, in one instance resulting in eight additional hours spent on debugging code.

Due to our proactive defense efforts, FlyingYeti operators adapted their tactics multiple times in their attempts to launch the campaign. The actor originally intended to have the Cloudflare Worker fetch the malicious RAR file from GitHub. After Cloudforce One interdiction of the Worker, the actor attempted to create additional Workers via a new account. In response, we disabled all Workers, leading the actor to load the RAR file directly from GitHub. Cloudforce One notified GitHub, resulting in the takedown of the RAR file, the GitHub project, and suspension of the account used to host the RAR file. In return, FlyingYeti began testing the option to host the RAR file on the file sharing sites pixeldrain and Filemail, where we observed the actor alternating the link on the Komunalka phishing site between the following:

  • hxxps://pixeldrain[.]com/api/file/ZAJxwFFX?download=one
  • hxxps://1014.filemail[.]com/api/file/get?filekey=e_8S1HEnM5Rzhy_jpN6nL-GF4UAP533VrXzgXjxH1GzbVQZvmpFzrFA&pk_vid=a3d82455433c8ad11715865826cf18f6

We notified GitHub of the actor’s evolving tactics, and in response GitHub removed the Komunalka phishing site. After analyzing the files hosted on pixeldrain and Filemail, we determined the actor uploaded dummy payloads, likely to monitor access to their phishing infrastructure (FileMail logs IP addresses, and both file hosting sites provide view and download counts). At the time of publication, we did not observe FlyingYeti upload the malicious RAR file to either file hosting site, nor did we identify the use of alternative phishing or malware delivery methods.

A timeline of FlyingYeti’s activity and our corresponding mitigations can be found below.

Event timeline

Date Event Description
2024-04-18 12:18 Threat Actor (TA) creates a Worker to handle requests from a phishing site
2024-04-18 14:16 TA creates phishing site komunalka[.]github[.]io on GitHub
2024-04-25 12:25 TA creates a GitHub repo to host a RAR file
2024-04-26 07:46 TA updates the first Worker to handle requests from users visiting komunalka[.]github[.]io
2024-04-26 08:24 TA uploads a benign test RAR to the GitHub repo
2024-04-26 13:38 Cloudforce One identifies a Worker receiving requests from users visiting komunalka[.]github[.]io, observes its use as a phishing page
2024-04-26 13:46 Cloudforce One identifies that the Worker fetches a RAR file from GitHub (the malicious RAR payload is not yet hosted on the site)
2024-04-26 19:22 Cloudforce One creates a detection to identify the Worker that fetches the RAR
2024-04-26 21:13 Cloudforce One deploys real-time monitoring of the RAR file on GitHub
2024-05-02 06:35 TA deploys a weaponized RAR (CVE-2023-38831) to GitHub with their COOKBOX malware packaged in the archive
2024-05-06 10:03 TA attempts to update the Worker with link to weaponized RAR, the Worker is immediately blocked
2024-05-06 10:38 TA creates a new Worker, the Worker is immediately blocked
2024-05-06 11:04 TA creates a new account (#2) on Cloudflare
2024-05-06 11:06 TA creates a new Worker on account #2 (blocked)
2024-05-06 11:50 TA creates a new Worker on account #2 (blocked)
2024-05-06 12:22 TA creates a new modified Worker on account #2
2024-05-06 16:05 Cloudforce One disables the running Worker on account #2
2024-05-07 22:16 TA notices the Worker is blocked, ceases all operations
2024-05-07 22:18 TA deletes original Worker first created to fetch the RAR file from the GitHub phishing page
2024-05-09 19:28 Cloudforce One adds phishing page komunalka[.]github[.]io to real-time monitoring
2024-05-13 07:36 TA updates the github.io phishing site to point directly to the GitHub RAR link
2024-05-13 17:47 Cloudforce One adds COOKBOX C2 postdock[.]serveftp[.]com to real-time monitoring for DNS resolution
2024-05-14 00:04 Cloudforce One notifies GitHub to take down the RAR file
2024-05-15 09:00 GitHub user, project, and link for RAR are no longer accessible
2024-05-21 08:23 TA updates Komunalka phishing site on github.io to link to pixeldrain URL for dummy payload (pixeldrain only tracks view and download counts)
2024-05-21 08:25 TA updates Komunalka phishing site to link to FileMail URL for dummy payload (FileMail tracks not only view and download counts, but also IP addresses)
2024-05-21 12:21 Cloudforce One downloads PixelDrain document to evaluate payload
2024-05-21 12:47 Cloudforce One downloads FileMail document to evaluate payload
2024-05-29 23:59 GitHub takes down Komunalka phishing site
2024-05-30 13:00 Cloudforce One publishes the results of this investigation

Coordinating our FlyingYeti response

Cloudforce One leveraged industry relationships to provide advanced warning and to mitigate the actor’s activity. To further protect the intended targets from this phishing threat, Cloudforce One notified and collaborated closely with GitHub’s Threat Intelligence and Trust and Safety Teams. We also notified CERT-UA and Cloudflare industry partners such as CrowdStrike, Mandiant/Google Threat Intelligence, and Microsoft Threat Intelligence.

Hunting FlyingYeti operations

There are several ways to hunt FlyingYeti in your environment. These include using PowerShell to hunt for WinRAR files, deploying Microsoft Sentinel analytics rules, and running Splunk scripts as detailed below. Note that these detections may identify activity related to this threat, but may also trigger unrelated threat activity.

PowerShell hunting

Consider running a PowerShell script such as this one in your environment to identify exploitation of CVE-2023-38831. This script will interrogate WinRAR files for evidence of the exploit.

CVE-2023-38831
Description:winrar exploit detection 
open suspios (.tar / .zip / .rar) and run this script to check it 

function winrar-exploit-detect(){
$targetExtensions = @(".cmd" , ".ps1" , ".bat")
$tempDir = [System.Environment]::GetEnvironmentVariable("TEMP")
$dirsToCheck = Get-ChildItem -Path $tempDir -Directory -Filter "Rar*"
foreach ($dir in $dirsToCheck) {
    $files = Get-ChildItem -Path $dir.FullName -File
    foreach ($file in $files) {
        $fileName = $file.Name
        $fileExtension = [System.IO.Path]::GetExtension($fileName)
        if ($targetExtensions -contains $fileExtension) {
            $fileWithoutExtension = [System.IO.Path]::GetFileNameWithoutExtension($fileName); $filename.TrimEnd() -replace '\.$'
            $cmdFileName = "$fileWithoutExtension"
            $secondFile = Join-Path -Path $dir.FullName -ChildPath $cmdFileName
            
            if (Test-Path $secondFile -PathType Leaf) {
                Write-Host "[!] Suspicious pair detected "
                Write-Host "[*]  Original File:$($secondFile)" -ForegroundColor Green 
                Write-Host "[*] Suspicious File:$($file.FullName)" -ForegroundColor Red

                # Read and display the content of the command file
                $cmdFileContent = Get-Content -Path $($file.FullName)
                Write-Host "[+] Command File Content:$cmdFileContent"
            }
        }
    }
}
}
winrar-exploit-detect

Microsoft Sentinel

In Microsoft Sentinel, consider deploying the rule provided below, which identifies WinRAR execution via cmd.exe. Results generated by this rule may be indicative of attack activity on the endpoint and should be analyzed.

DeviceProcessEvents
| where InitiatingProcessParentFileName has @"winrar.exe"
| where InitiatingProcessFileName has @"cmd.exe"
| project Timestamp, DeviceName, FileName, FolderPath, ProcessCommandLine, AccountName
| sort by Timestamp desc

Splunk

Consider using this script in your Splunk environment to look for WinRAR CVE-2023-38831 execution on your Microsoft endpoints. Results generated by this script may be indicative of attack activity on the endpoint and should be analyzed.

| tstats `security_content_summariesonly` count min(_time) as firstTime max(_time) as lastTime from datamodel=Endpoint.Processes where Processes.parent_process_name=winrar.exe `windows_shells` OR Processes.process_name IN ("certutil.exe","mshta.exe","bitsadmin.exe") by Processes.dest Processes.user Processes.parent_process_name Processes.parent_process Processes.process_name Processes.process Processes.process_id Processes.parent_process_id 
| `drop_dm_object_name(Processes)` 
| `security_content_ctime(firstTime)` 
| `security_content_ctime(lastTime)` 
| `winrar_spawning_shell_application_filter`

Cloudflare product detections

Cloudflare Email Security

Cloudflare Email Security (CES) customers can identify FlyingYeti threat activity with the following detections.

  • CVE-2023-38831
  • FLYINGYETI.COOKBOX
  • FLYINGYETI.COOKBOX.Launcher
  • FLYINGYETI.Rar

Recommendations

Cloudflare recommends taking the following steps to mitigate this type of activity:

  • Implement Zero Trust architecture foundations:    
  • Deploy Cloud Email Security to ensure that email services are protected against phishing, BEC and other threats
  • Leverage browser isolation to separate messaging applications like LinkedIn, email, and Signal from your main network
  • Scan, monitor and/or enforce controls on specific or sensitive data moving through your network environment with data loss prevention policies
  • Ensure your systems have the latest WinRAR and Microsoft security updates installed
  • Consider preventing WinRAR files from entering your environment, both at your Cloud Email Security solution and your Internet Traffic Gateway
  • Run an Endpoint Detection and Response (EDR) tool such as CrowdStrike or Microsoft Defender for Endpoint to get visibility into binary execution on hosts
  • Search your environment for the FlyingYeti indicators of compromise (IOCs) shown below to identify potential actor activity within your network.

If you’re looking to uncover additional Threat Intelligence insights for your organization or need bespoke Threat Intelligence information for an incident, consider engaging with Cloudforce One by contacting your Customer Success manager or filling out this form.

Indicators of Compromise

Filename SHA256 Hash Description
Заборгованість по ЖКП.rar a0a294f85c8a19be048ffcc05ede6fd5a7ac5e2f0032a3ca0050dc1ae960c314 RAR archive
Рахунок на оплату.pdf
                                                                                 .cmd
0cca8f795c7a81d33d36d5204fcd9bc73bdc2af7de315c1449cbc3551ef4fb59 COOKBOX Sample (contained in RAR archive)
Реструктуризація боргу за житлово комунальні послуги.docx 915721b94e3dffa6cef3664532b586be6cf989fec923b26c62fdaf201ee81d2c Benign Word Document with Tracking Link (contained in RAR archive)
Угода користувача.docx 79a9740f5e5ea4aa2157d9d96df34ee49a32e2d386fe55fedfd1aa33e151c06d Benign Word Document with Tracking Link (contained in RAR archive)
Рахунок на оплату.pdf 19e25456c2996ded3e29577b609de54a2bef90dad8f868cdad795c18df05a79b Random Binary Data (contained in RAR archive)
Заборгованість по ЖКП станом на 26.04.24.docx e0d65e2d36afd3db1b603f10e0488cee3f58ade24d8abc6bee240314d8696708 Random Binary Data (contained in RAR archive)
Domain / URL Description
komunalka[.]github[.]io Phishing page
hxxps[:]//github[.]com/komunalka/komunalka[.]github[.]io Phishing page
hxxps[:]//worker-polished-union-f396[.]vqu89698[.]workers[.]dev Worker that fetches malicious RAR file
hxxps[:]//raw[.]githubusercontent[.]com/kudoc8989/project/main/Заборгованість по ЖКП.rar Delivery of malicious RAR file
hxxps[:]//1014[.]filemail[.]com/api/file/get?filekey=e_8S1HEnM5Rzhy_jpN6nL-GF4UAP533VrXzgXjxH1GzbVQZvmpFzrFA&pk_vid=a3d82455433c8ad11715865826cf18f6 Dummy payload
hxxps[:]//pixeldrain[.]com/api/file/ZAJxwFFX?download= Dummy payload
hxxp[:]//canarytokens[.]com/stuff/tags/ni1cknk2yq3xfcw2al3efs37m/payments.js Tracking link
hxxp[:]//canarytokens[.]com/stuff/terms/images/k22r2dnjrvjsme8680ojf5ccs/index.html Tracking link
postdock[.]serveftp[.]com COOKBOX C2

Using the circuit-breaker pattern with AWS Lambda extensions and Amazon DynamoDB

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/using-the-circuit-breaker-pattern-with-aws-lambda-extensions-and-amazon-dynamodb/

This post is written by Alan Oberto Jimenez, Senior Cloud Application Architect, and Tobias Drees, Cloud Application Architect.

Modern software systems frequently rely on remote calls to other systems across networks. When failures occur, they can cascade across multiple services causing service disruptions. One technique for mitigating this risk is the circuit breaker pattern, which can detect and isolate failures in a distributed system. The circuit breaker pattern can help prevent cascading failures and improve overall system stability.

The pattern isolates the failing service and thus prevents cascading failures. It improves the overall responsiveness by preventing long waiting times for timeout periods. Furthermore, it also increases the fault tolerance of the system since it lets the system interact with the affected service again once it is available again.

This blog post presents an example application, showing how AWS Lambda extensions integrate with Amazon DynamoDB to implement the circuit breaker pattern.

Using Lambda extensions to implement the circuit breaker pattern

AWS Lambda extensions provide a way to integrate monitoring, observability, security, and governance tools into the Lambda execution environment without complex installation or configuration management. You can run extensions both as part of the runtime process with an internal extension or as a separate process in the execution environment with an external extension.

Lambda extensions enable the circuit breaker pattern without modifying the core function code. An external extension checks in a separate runtime whether a certain service is reachable or not. This approach decouples the business logic in the Lambda function from failure detection, allowing for the reuse of this Lambda extension across different Lambda functions. Both decoupling of code with different purposes and code reuse is in line with the best practices for building Lambda functions.

Pinging a microservice at each Lambda invocation increases network traffic and latency. Circuit breaker implementations benefit from a caching layer to store the state of the microservices. The Lambda extension fetches the status of a microservice from a database and stores the result in memory for a specified time avoiding a disk write. The Lambda function checks the extension cache before pinging the microservice reducing network traffic. Lambda extensions are an ideal tool to build a caching layer for Lambda functions since its in-memory cache makes it more secure, easier to manage, and more performant due to higher availability compared to calling a network resource instead.

Overview

Architecture Overview

  1. The main function process handles the event after every AWS Lambda invocation. Before performing any external call against the external components, it listens for HTTP POST events from the Lambda extension process to fetch the last status of the circuits.
  2. The extension process provides the circuit state to the main process via HTTP POST.
    1. The extension checks its internal cache and returns a valid value if available, otherwise reads the state of the circuits from the DynamoDB table and updates the cache.
    2. Finally, the extension process returns the state of the circuits to the main function via an API call response.
    3. Because of the Lambda extensions lifecycle, this process occurs periodically to keep the local cache updated until the execution environment is terminated.
  3. If the circuit is in the OPEN state, the main function process executes calls against the external microservices, otherwise the process returns a local response.
  4. An Amazon EventBridge event periodically invokes a Lambda responsible for updating the circuit states.
  5. This Lambda function performs the validations needed to determine the status of the different remote microservices (circuits) with an Amazon API Gateway entrypoint.
  6. The Lambda function writes the result of the verification process to the DynamoDB table.

Walkthrough

The following prerequisites are required to complete the walkthrough:

  • An active AWS account
  • AWS CLI 2.15.17 or later
  • AWS SAM CLI 1.116.0 or later
  • Git 2.39.3 or later
  • Python 3.12

Initial setup

  1. Clone the code from GitHub onto a local machine:
    git clone https://github.com/aws-samples/implementing-the-circuit-breaker-pattern-with-lambda-extensions-and-dynamodb.git
  2. To install the packages, utilize a virtual environment:
    python -m venv circuit_breaker_venv && source circuit_breaker_venv/bin/activate
  3. To prepare the services for deployment, execute the following AWS Serverless Application Model (SAM) command:
    sam build
  4. To deploy the services, use this command specifying the AWS CLI profile (in the config file in the .aws folder) for the AWS account to deploy the services in:
    sam deploy --guided --profile <AWSProfile>

    Answer the question prompts as appropriate.

  5. You can deploy subsequent local changes in the code with:
    sam build 
    sam deploy

Testing and adjusting the solution

The Lambda function updating the state in DynamoDB runs every minute as specified by the template. After the function has run for the first time after 1 minute, the DynamoDB entry containing the status (“OPEN” or “CLOSED”) is ready. Since the mock API is part of the stack, the status is “OPEN”.

You can invoke the My Microservice Lambda function manually to see:

Response

The Lambda function updating the state in DynamoDB is invoked with an EventBridge rule that specifies the URL and the ID of the service to be monitored. By creating a new EventBridge rule with the correct URL and a new ID, you can use the AWS SAM template for monitoring multiple services.

To add a new EventBridge rule, add this to the template:

  NewEventRule:
    Type: AWS::Events::Rule
    Properties:
      Description: Event rule to trigger the Lambda function with a JSON payload
      ScheduleExpression: rate(1 minute) 
      State: ENABLED
      Targets:
        - Arn: !GetAtt UpdatingStateLambda.Arn
          Id: TargetFunction
          Input: '{ "URL": "https://aws.amazon.com/", "ID": "NewMicroservice"}'  # Add the JSON payload here

  MyPermissionForNewEventRule:
    Type: AWS::Lambda::Permission
    Properties:
      FunctionName: !Ref UpdatingStateLambda
      Action: lambda:InvokeFunction
      Principal: events.amazonaws.com
      SourceArn: !GetAtt NewEventRule.Arn    

In the Lambda function that contains the business logic, add the following environment variables. However, for more complex cases with multiple microservices to be monitored, it’s recommended to use AWS Config. Using AWS Config, configurations for Lambda functions can be stored to enable more granular control than with environment variables.

Environment:
        Variables:
          service_name: "NewMicroservice"

You can adjust the logic of this Lambda function by changing the code in my-microservice/lambda-handler.py or directly in the Lambda section of the AWS Management Console.

If you end up using your own Lambda function to use the circuit breaker Lambda extension, include the circuit breaker extension as a layer:

BusinessLogicMicroservice:
    Type: AWS::Serverless::Function
    Properties:
      CodeUri: business-logic-microservice/
      Handler: lambda_function.lambda_handler
      MemorySize: 128
      Policies:
      - DynamoDBCrudPolicy:
          TableName: !Ref CircuitBreakerStateTable
      Timeout: 100
      Runtime: python3.8
      Layers:
      - !Ref CircuitBreakerExtensionLayer

Circuit breaker in closed state

So far, the sample application only features an open circuit breaker state signaling a functioning microservice. This section simulates an unresponsive microservice to test the behavior of the system with a closed-circuit breaker state.

  1. Edit the environment variables of the MyMicroservice Lambda function in line 47 of the template.yaml file and the URL of the input to the Lambda updating the state in the event rule in line 107 to a domain that times out such as ”https://aws.amazon.com:81/“.
    API_URL: "https://aws.amazon.com:81/"
    Input: '{ "URL": "https://aws.amazon.com:81/", "ID": "MyMicroservice"}'
    
  2. Deploy these changes:
    sam build
    sam deploy

The event rule invokes the Lambda function, updating the state every minute. To see the output of this Lambda function, invoke it manually:

Execution result

This Lambda function changes the DynamoDB entry for this URL to:

DynamoDB entry

The MyMicroservice Lambda function receives the DynamoDB entries for the status over HTTP from the Circuit Breaker Lambda extension and proceeds with the logic following a closed state. The output of invoking the Lambda manually is:

Manual output

This shows the circuit breaker pattern working as intended. In the Lambda updating state, the time it takes for the Lambda function to throw a timeout exception is defined as 4 seconds and can be adjusted to the use case.

requests.get(API_URL, headers=headers, timeout=4)

Clean-up

To delete all resources from this stack, run:

sam delete --stack-name new-circuit-breaker-sam-stack

Security

The provided AWS SAM template does not provide an Amazon Virtual Private Cloud (VPC) in which to host the resources. Integrate the resources into an appropriate networking configuration if you are using it in production applications.

The solution has auditability characteristics, as calls to the circuit breaker and to the microservices are logged to the Amazon CloudWatch log group. The audit log is encrypted using AWS Key Management Service.

To monitor the security of your account with the solution, use Amazon GuardDuty, AWS CloudTrail, AWS Config, and AWS WAF for API Gateway.

Conclusion

The circuit breaker pattern is a powerful tool for helping to ensure the resiliency and stability of serverless applications. Lambda extensions are a good fit for its implementation, as demonstrated in this example. With the provided Lambda extension and code, you can incorporate the circuit breaker pattern into your applications and customize it to suit your specific requirements, helping to ensure a robust and reliable system.

For more serverless learning resources, visit Serverless Land.