Tag Archives: Uncategorized

Building a Cloud in the Cloud: Running Apache CloudStack on Amazon EC2, Part 1

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/building-a-cloud-in-the-cloud-running-apache-cloudstack-on-amazon-ec2-part-1/

This blog is written by Mark Rogers, SDE II – Customer Engineering AWS.

How do you put a cloud inside another cloud? Some features that make Amazon Elastic Compute Cloud (Amazon EC2) secure and wonderful also make running CloudStack difficult. The biggest obstacle is that AWS and CloudStack both want to manage network resources. Therefore, we must keep them out of each other’s way. This requires some steps that aren’t obvious, and it took a long time to figure out. I’m going to share what I learned, so that you can navigate the process more easily.

Apache CloudStack is an open-source platform for deploying and managing virtual machines (VMs) and the associated network and storage infrastructure. You would normally run it on your own hardware to create your own cloud. But there can be advantages to running it inside of an Amazon Virtual Private Cloud (Amazon VPC), including how it could help you migrate out of a data center. It’s a great way to create disposable environments for experiments or training. Furthermore, it’s a convenient way to test-drive the new CloudStack support in Amazon Elastic Kubernetes Service (Amazon EKS) Anywhere. In my case, I needed to create development and test environments for a project that uses the CloudStack API. The environments needed to be shared and scalable. Our build pipelines were already in AWS, so it made sense to put the new environments there, too.

CloudStack can work with a number of hypervisors. The instructions in this article will use Kernel-based Virtual Machine (KVM) on Linux. KVM will manage the VMs at a low level, and CloudStack will manage KVM.

Prerequisites

Most of the information in this article should be applicable to a range of CloudStack versions. I targeted CloudStack 4.14 on CentOS 7. I also tested CloudStack versions 4.16 and 4.17, and I recommend them.

The official CentOS 7 x86_64 HVM image works well. If you use a different Linux flavor or version, then you might have to modify some of the implementation details.

You’ll need to know the basics of CloudStack. The scope of this article is making CloudStack and AWS coexist peacefully. Once CloudStack is running, I’m assuming that you’ll handle things from there.  Refer to the AWS documentation and CloudStack documentation for information on security and other best practices.

Making things easier

I wrote some scripts to automate the installation. You can run them on EC2 instances with CentOS 7, and they’ll do all the installation and OS configuration for you. You can use them as they are, or customize them to meet your needs. I also wrote some AWS CloudFormation templates you can copy in order to create a demo environment. The README file has more details.

Amazon EC2 instance types

KVM requires hardware virtualization support. Most EC2 instances are VMs that don’t support nested virtualization. To get access to the bare hardware, you need a metal instance type.

I like c5.metal because it’s one of the least expensive metal types, and has a low cost per vCPU. It has 96 vCPUs and 192 GiB of memory. If you run 20 VMs on it, with 4 CPU cores and 8 GiB of memory each, then you’d still have 16 vCPUs and 32 GiB to share between the operating system, CloudStack, and MySQL. Using CloudStack’s overprovisioning feature, you could fit even more VMs if they’re running light loads.

Networking

The biggest challenge is the network. AWS knows which IP and MAC addresses should exist, and it knows the machines to which they should belong. It blocks any traffic that doesn’t fit its idea of how the network should behave. Simultaneously, CloudStack assumes that any IP or MAC address it invents should work just fine. When CloudStack assigns addresses to VMs on an AWS subnet, their network traffic gets blocked.

You could get around this by enabling network address translation (NAT) on the instance running CloudStack. That’s a great solution if it fits your needs, but it makes it hard for other machines in your Amazon VPC to contact your VMs. I recommend a different approach.

Although AWS restricts what you can do with its layer 2 network, it’s perfectly happy to let you run your own layer 3 router. Your EC2 instance can act as a router to a new virtual subnet that’s outside of the jurisdiction of AWS. The instance integrates with AWS just like a VPN appliance, routing traffic to wherever it needs to go. CloudStack can do whatever it wants in the virtual subnet, and everybody’s happy.

What do I mean by a virtual subnet? This is a subnet that exists only inside the EC2 instance.  It consists of logical network interfaces attached to a Linux bridge. The entire subnet exists inside a single EC2 instance. It doesn’t scale well, but it’s simple. In my next post, I’ll cover a more complicated setup with an overlay network that spans multiple instances to allow horizontal scaling.

The simple way

The simple way is to put everything in one EC2 instance, including the database, file storage, and a virtual subnet. Because everything’s stored locally, allocate enough disk space for your needs. 500 GB will be enough to support a few basic VMs. Create or select a security group for your instance that gives users access to the CloudStack UI (TCP port 8080). The security group should also allow access to any services that you’ll offer from your VMs.

EC2 instance summary info showing 1 instance, CentOS 7 (x86_64) AMI, c5.metal instance type, a security group name, and a 500 GiB volume

When you have your instance, configure AWS to treat it as a router.

  1. Go to Amazon EC2 in the AWS Management Console.
  2. Select your instance, and stop source/destination checking.

In the EC2 Actions menu, select Networking, then Change source/destination check.

3. Update the subnet route tables.

a. Go to the VPC settings, and select Route Tables.

b. Identify the tables for subnets that need CloudStack access.

c. In each of these tables, add a route to the new virtual subnet. The route target should be your EC2 instance.

4. Depending on your network needs, you may also need to add routes to transit gateways, VPN endpoints, etc.

Because everything will be on one server, creating a virtual subnet is simply a matter of creating a Linux bridge. CloudStack must find a network adapter attached to the bridge. Therefore, add a dummy interface with a name that CloudStack will recognize.
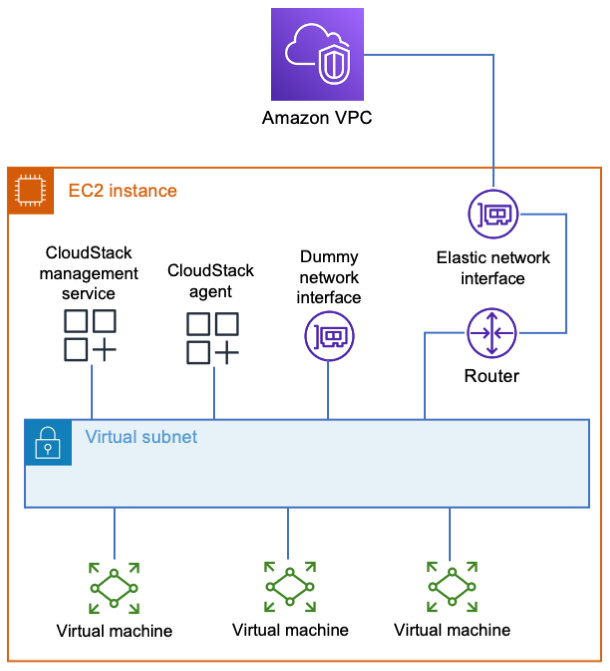
A single EC2 instance contains the CloudStack management service, the CloudStack agent, a dummy network interface, several virtual machines, and a router. All of those things are connected to each other by a virtual subnet that exists inside the instance. The instance's elastic network interface is connected between the router and the Amazon VPC.The following snippet shows how I configure networking in CentOS 7. You must provide values for the variables $virutal_host_ip_address and $virtual_netmask to reflect the virtual subnet that you want to create. For $dns_address, I recommend the base of the VPC IPv4 network range, plus two. You shouldn’t use 169.654.169.253 because CloudStack reserves link-local addresses for its own use.

yum install -y bridge-utils net-tools

# The bridge must be named cloudbr0.

cat << EOF > /etc/sysconfig/network-scripts/ifcfg-cloudbr0
DEVICE=cloudbr0
TYPE=Bridge
ONBOOT=yes
BOOTPROTO=none
IPV6INIT=no
IPV6_AUTOCONF=no
DELAY=5
STP=yes
USERCTL=no
NM_CONTROLLED=no
IPADDR=$virtual_host_ip_address
NETMASK=$virtual_netmask
DNS1=$dns_address
EOF

# Create a dummy network interface.
cat << EOF > /etc/sysconfig/modules/dummy.modules
#!/bin/sh
/sbin/modprobe dummy numdummies=1
/sbin/ip link set name ethdummy0 dev dummy0
EOF

chmod +x /etc/sysconfig/modules/dummy.modules
/etc/sysconfig/modules/dummy.modules

cat << EOF > /etc/sysconfig/network-scripts/ifcfg-ethdummy0
TYPE=Ethernet
BOOTPROTO=none
NAME=ethdummy0
DEVICE=ethdummy0
ONBOOT=yes
BRIDGE=cloudbr0
NM_CONTROLLED=no
EOF

# Turn the instance into a router

echo 'net.ipv4.ip_forward=1' >> /etc/sysctl.conf
sysctl -p

# Must kill dhclient or the network service won't restart properly.
# A reboot would also work, if you’d rather do that.

pkill dhclient
systemctl restart network

CloudStack must know which IP addresses to use for inter-service communication. It will select by resolving the machine’s fully qualified domain name (FQDN) to an address. The following commands will make it to choose the right one. You must provide a value for $virtual_host_ip_address.

hostnamectl set-hostname cloudstack.localdomain

echo "$virtual_host_ip_address cloudstack.localdomain" >> 
/etc/hosts

You can finish the setup by following the Quick Installation Guide.

Remember that CloudStack is only directly connected to your virtual network. The EC2 instance is the router that connects the virtual subnet to the Amazon VPC. When you’re configuring CloudStack, use your instance’s virtual subnet address as the default gateway.

Use the EC2 instance's virtual subnet IP address as the default gateway in CloudStack. In this example, the virtual subnet is 10.100.0.0/16, and the instance's address in that subnet is 10.100.0.1. CloudStack then uses 10.100.0.1 as the default gateway.

To access CloudStack from your workstation, you’ll need a connection to your VPC. This can be through a client VPN or a bastion host. If you use a bastion, its subnet needs a route to your virtual subnet, and you’ll need an SSH tunnel for your browser to access the CloudStack UI. The UI is at http://x.x.x.x:8080/client/, where x.x.x.x is your CloudStack instance’s virtual subnet address. Note that CloudStack’s console viewer won’t work if you’re using an SSH tunnel.

If you’re just experimenting with CloudStack, then I suggest saving money by stopping your instance when it isn’t needed. The safe way to do that is:

  1. Disable your zone in the CloudStack UI.
  2. Put the primary storage into maintenance mode.
  3. Wait for the switch to maintenance mode to be complete.
  4. Stop the EC2 instance.

When you’re ready to turn everything back on, simply reverse those steps. If you have any virtual routers in CloudStack, then you may need to start those, too.

Cleanup

If you used my CloudFormation template, then delete the stack and remove any route table entries you added. If you didn’t use CloudFormation, then terminate the EC2 instance, delete the security group you created for it, and remove any route table entries that you added.

Conclusion

Getting CloudStack to run on AWS isn’t so bad. The hardest part is simply knowing how. The setup explained here is great for small installations, but it can only scale vertically. In my next post, I’ll show you how to create an installation that scales horizontally. Instead of using a virtual subnet that exists in a single EC2 instance, we’ll build an overlay network that spans multiple instances. It will use more components and features, including some that might be new to you. I hope you find it interesting!

Now that you can create a simple setup, give it a try! I hope you have fun and learn something new along the way. Comment with the results of your experiments.

“Apache”, “Apache CloudStack”, and “CloudStack” are trademarks of the Apache Software Foundation.
Decarbonizing Cryptocurrencies through Taxation

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/01/decarbonizing-cryptocurrencies-through-taxation.html

Maintaining bitcoin and other cryptocurrencies causes about 0.3 percent of global CO2 emissions. That may not sound like a lot, but it’s more than the emissions of Switzerland, Croatia, and Norway combined. As many cryptocurrencies crash and the FTX bankruptcy moves into the litigation stage, regulators are likely to scrutinize the cryptocurrency world more than ever before. This presents a perfect opportunity to curb their environmental damage.

The good news is that cryptocurrencies don’t have to be carbon intensive. In fact, some have near-zero emissions. To encourage polluting currencies to reduce their carbon footprint, we need to force buyers to pay for their environmental harms through taxes.

The difference in emissions among cryptocurrencies comes down to how they create new coins. Bitcoin and other high emitters use a system called “proof of work“: to generate coins, participants, or “miners,” have to solve math problems that demand extraordinary computing power. This allows currencies to maintain their decentralized ledger—the blockchain—but requires enormous amounts of energy.

Greener alternatives exist. Most notably, the “proof of stake” system enables participants to maintain their blockchain by depositing cryptocurrency holdings in a pool. When the second-largest cryptocurrency, Ethereum, switched from proof of work to proof of stake earlier this year, its energy consumption dropped by more than 99.9% overnight.

Bitcoin and other cryptocurrencies probably won’t follow suit unless forced to, because proof of work offers massive profits to miners—and they’re the ones with power in the system. Multiple legislative levers could be used to entice them to change.

The most blunt solution is to ban cryptocurrency mining altogether. China did this in 2018, but it only made the problem worse; mining moved to other countries with even less efficient energy generation, and emissions went up. The only way for a mining ban to meaningfully reduce carbon emissions is to enact it across most of the globe. Achieving that level of international consensus is, to say the least, unlikely.

A second solution is to prohibit the buying and selling of proof-of-work currencies. The European Parliament’s Committee on Economic and Monetary Affairs considered making such a proposal, but voted against it in March. This is understandable; as with a mining ban, it would be both viewed as paternalistic and difficult to implement politically.

Employing a tax instead of an outright ban would largely skirt these issues. As with taxes on gasoline, tobacco, plastics, and alcohol, a cryptocurrency tax could reduce real-world harm by making consumers pay for it.

Most ways of taxing cryptocurrencies would be inefficient, because they’re easy to circumvent and hard to enforce. To avoid these pitfalls, the tax should be levied as a fixed percentage of each proof-of-work-cryptocurrency purchase. Cryptocurrency exchanges should collect the tax, just as merchants collect sales taxes from customers before passing the sum on to governments. To make it harder to evade, the tax should apply regardless of how the proof-of-work currency is being exchanged—whether for a fiat currency or another cryptocurrency. Most important, any state that implements the tax should target all purchases by citizens in its jurisdiction, even if they buy through exchanges with no legal presence in the country.

This sort of tax would be transparent and easy to enforce. Because most people buy cryptocurrencies from one of only a few large exchanges—such as Binance, Coinbase, and Kraken—auditing them should be cheap enough that it pays for itself. If an exchange fails to comply, it should be banned.

Even a small tax on proof-of-work currencies would reduce their damage to the planet. Imagine that you’re new to cryptocurrency and want to become a first-time investor. You’re presented with a range of currencies to choose from: bitcoin, ether, litecoin, monero, and others. You notice that all of them except ether add an environmental tax to your purchase price. Which one do you buy?

Countries don’t need to coordinate across borders for a proof-of-work tax on their own citizens to be effective. But early adopters should still consider ways to encourage others to come on board. This has precedent. The European Union is trying to influence global policy with its carbon border adjustments, which are designed to discourage people from buying carbon-intensive products abroad in order to skirt taxes. Similar rules for a proof-of-work tax could persuade other countries to adopt one.

Of course, some people will try to evade the tax, just as people evade every other tax. For example, people might buy tax-free coins on centralized exchanges and then swap them for polluting coins on decentralized exchanges. To some extent, this is inevitable; no tax is perfect. But the effort and technical know-how needed to evade a proof-of-work tax will be a major deterrent.

Even if only a few countries implement this tax—and even if some people evade it—the desirability of bitcoin will fall globally, and the environmental benefit will be significant. A high enough tax could also cause a self-reinforcing cycle that will drive down these cryptocurrencies’ prices. Because the value of many cryptocurrencies rely largely on speculation, they are dependent on future buyers. When speculators are deterred by the tax, the lack of demand will cause the price of bitcoin to fall, which could prompt more current holders to sell—further lowering prices and accelerating the effect. Declining prices will pressure the bitcoin community to abandon proof of work altogether.

Taxing proof-of-work exchanges might hurt them in the short run, but it would not hinder blockchain innovation. Instead, it would redirect innovation toward greener cryptocurrencies. This is no different than how government incentives for electric vehicles encourage carmakers to improve green alternatives to the internal combustion engine. These incentives don’t restrict innovation in automobiles—they promote it.

Taxing environmentally harmful cryptocurrencies can gain support across the political spectrum, from people with varied interests. It would benefit blockchain innovators and cryptocurrency researchers by shifting focus from environmental harm to beneficial uses of the technology. It has the potential to make our planet significantly greener. It would increase government revenues.

Even bitcoin maximalists have reason to embrace the proposal: it would offer the bitcoin community a chance to prove it can survive and grow sustainably.

This essay was written with Christos Porios, and previously appeared in the Atlantic.

Breaking RSA with a Quantum Computer

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/01/breaking-rsa-with-a-quantum-computer.html

A group of Chinese researchers have just published a paper claiming that they can—although they have not yet done so—break 2048-bit RSA. This is something to take seriously. It might not be correct, but it’s not obviously wrong.

We have long known from Shor’s algorithm that factoring with a quantum computer is easy. But it takes a big quantum computer, on the orders of millions of qbits, to factor anything resembling the key sizes we use today. What the researchers have done is combine classical lattice reduction factoring techniques with a quantum approximate optimization algorithm. This means that they only need a quantum computer with 372 qbits, which is well within what’s possible today. (The IBM Osprey is a 433-qbit quantum computer, for example. Others are on their way as well.)

The Chinese group didn’t have that large a quantum computer to work with. They were able to factor 48-bit numbers using a 10-qbit quantum computer. And while there are always potential problems when scaling something like this up by a factor of 50, there are no obvious barriers.

Honestly, most of the paper is over my head—both the lattice-reduction math and the quantum physics. And there’s the nagging question of why the Chinese government didn’t classify this research. But…wow…maybe…and yikes! Or not.

“Factoring integers with sublinear resources on a superconducting quantum processor”

Abstract: Shor’s algorithm has seriously challenged information security based on public key cryptosystems. However, to break the widely used RSA-2048 scheme, one needs millions of physical qubits, which is far beyond current technical capabilities. Here, we report a universal quantum algorithm for integer factorization by combining the classical lattice reduction with a quantum approximate optimization algorithm (QAOA). The number of qubits required is O(logN/loglogN ), which is sublinear in the bit length of the integer N , making it the most qubit-saving factorization algorithm to date. We demonstrate the algorithm experimentally by factoring integers up to 48 bits with 10 superconducting qubits, the largest integer factored on a quantum device. We estimate that a quantum circuit with 372 physical qubits and a depth of thousands is necessary to challenge RSA-2048 using our algorithm. Our study shows great promise in expediting the application of current noisy quantum computers, and paves the way to factor large integers of realistic cryptographic significance.

In email, Roger Grimes told me: “Apparently what happened is another guy who had previously announced he was able to break traditional asymmetric encryption using classical computers…but reviewers found a flaw in his algorithm and that guy had to retract his paper. But this Chinese team realized that the step that killed the whole thing could be solved by small quantum computers. So they tested and it worked.”

EDITED TO ADD: One of the issues with the algorithm is that it relies on a recent factoring paper by Claus Schnorr. It’s a controversial paper; and despite the “this destroys the RSA cryptosystem” claim in the abstract, it does nothing of the sort. Schnorr’s algorithm works well with smaller moduli—around the same order as ones the Chinese group has tested—but falls apart at larger sizes. At this point, nobody understands why. The Chinese paper claims that their quantum techniques get around this limitation (I think that’s what’s behind Grimes’s comment) but don’t give any details—and they haven’t tested it with larger moduli. So if it’s true that the Chinese paper depends on this Schnorr technique that doesn’t scale, the techniques in this Chinese paper won’t scale, either. (On the other hand, if it does scale then I think it also breaks a bunch of lattice-based public-key cryptosystems.)

I am much less worried that this technique will work now. But this is something the IBM quantum computing people can test right now.

EDITED TO ADD (1/4): A reporter just asked me my gut feel about this. I replied that I don’t think this will break RSA. Several times a year the cryptography community received “breakthroughs” from people outside the community. That’s why we created the RSA Factoring Challenge: to force people to provide proofs of their claims. In general, the smart bet is on the new techniques not working. But someday, that bet will be wrong. Is it today? Probably not. But it could be. We’re in the worst possible position right now: we don’t have the facts to know. Someone needs to implement the quantum algorithm and see.

EDITED TO ADD (1/5): Scott Aaronson’s take is a “no”:

In the new paper, the authors spend page after page saying-without-saying that it might soon become possible to break RSA-2048, using a NISQ (i.e., non-fault-tolerant) quantum computer. They do so via two time-tested strategems:

  1. the detailed exploration of irrelevancies (mostly, optimization of the number of qubits, while ignoring the number of gates), and
  2. complete silence about the one crucial point.

Then, finally, they come clean about the one crucial point in a single sentence of the Conclusion section:

It should be pointed out that the quantum speedup of the algorithm is unclear due to the ambiguous convergence of QAOA.

“Unclear” is an understatement here. It seems to me that a miracle would be required for the approach here to yield any benefit at all, compared to just running the classical Schnorr’s algorithm on your laptop. And if the latter were able to break RSA, it would’ve already done so.

All told, this is one of the most actively misleading quantum computing papers I’ve seen in 25 years, and I’ve seen … many.

EDITED TO ADD (1/7): More commentary. Again: no need to panic.

EDITED TO ADD (1/12): Peter Shor has suspicions.

Develop a serverless application in Python using Amazon CodeWhisperer

Post Syndicated from Rafael Ramos original https://aws.amazon.com/blogs/devops/develop-a-serverless-application-in-python-using-amazon-codewhisperer/

While writing code to develop applications, developers must keep up with multiple programming languages, frameworks, software libraries, and popular cloud services from providers such as AWS. Even though developers can find code snippets on developer communities, to either learn from them or repurpose the code, manually searching for the snippets with an exact or even similar use case is a distracting and time-consuming process. They have to do all of this while making sure that they’re following the correct programming syntax and best coding practices.

Amazon CodeWhisperer, a machine learning (ML) powered coding aide for developers, lets you overcome those challenges. Developers can simply write a comment that outlines a specific task in plain English, such as “upload a file to S3.” Based on this, CodeWhisperer automatically determines which cloud services and public libraries are best-suited for the specified task, it creates the specific code on the fly, and then it recommends the generated code snippets directly in the IDE. And this isn’t about copy-pasting code from the web, but generating code based on the context of your file, such as which libraries and versions you have, as well as the existing code. Moreover, CodeWhisperer seamlessly integrates with your Visual Studio Code and JetBrains IDEs so that you can stay focused and never leave the development environment. At the time of this writing, CodeWhisperer supports Java, Python, JavaScript, C#, and TypeScript.

In this post, we’ll build a full-fledged, event-driven, serverless application for image recognition. With the aid of CodeWhisperer, you’ll write your own code that runs on top of AWS Lambda to interact with Amazon Rekognition, Amazon DynamoDB, Amazon Simple Notification Service (Amazon SNS), Amazon Simple Queue Service (Amazon SQS), Amazon Simple Storage Service (Amazon S3), and third-party HTTP APIs to perform image recognition. The users of the application can interact with it by either sending the URL of an image for processing, or by listing the images and the objects present on each image.

Solution overview

To make our application easier to digest, we’ll split it into three segments:

  1. Image download – The user provides an image URL to the first API. A Lambda function downloads the image from the URL and stores it on an S3 bucket. Amazon S3 automatically sends a notification to an Amazon SNS topic informing that a new image is ready for processing. Amazon SNS then delivers the message to an Amazon SQS queue.
  2. Image recognition – A second Lambda function handles the orchestration and processing of the image. It receives the message from the Amazon SQS queue, sends the image for Amazon Rekognition to process, stores the recognition results on a DynamoDB table, and sends a message with those results as JSON to a second Amazon SNS topic used in section three. A user can list the images and the objects present on each image by calling a second API which queries the DynamoDB table.
  3. 3rd-party integration – The last Lambda function reads the message from the second Amazon SQS queue. At this point, the Lambda function must deliver that message to a fictitious external e-mail server HTTP API that supports only XML payloads. Because of that, the Lambda function converts the JSON message to XML. Lastly, the function sends the XML object via HTTP POST to the e-mail server.

The following diagram depicts the architecture of our application:

Architecture diagram depicting the application architecture. It contains the service icons with the component explained on the text above

Figure 1. Architecture diagram depicting the application architecture. It contains the service icons with the component explained on the text above.

Prerequisites

Before getting started, you must have the following prerequisites:

Configure environment

We already created the scaffolding for the application that we’ll build, which you can find on this Git repository. This application is represented by a CDK app that describes the infrastructure according to the architecture diagram above. However, the actual business logic of the application isn’t provided. You’ll implement it using CodeWhisperer. This means that we already declared using AWS CDK components, such as the API Gateway endpoints, DynamoDB table, and topics and queues. If you’re new to AWS CDK, then we encourage you to go through the CDK workshop later on.

Deploying AWS CDK apps into an AWS environment (a combination of an AWS account and region) requires that you provision resources that the AWS CDK needs to perform the deployment. These resources include an Amazon S3 bucket for storing files and IAM roles that grant permissions needed to perform deployments. The process of provisioning these initial resources is called bootstrapping. The required resources are defined in an AWS CloudFormation stack, called the bootstrap stack, which is usually named CDKToolkit. Like any CloudFormation stack, it appears in the CloudFormation console once it has been deployed.

After cloning the repository, let’s deploy the application (still without the business logic, which we’ll implement later on using CodeWhisperer). For this post, we’ll implement the application in Python. Therefore, make sure that you’re under the python directory. Then, use the cdk bootstrap command to bootstrap an AWS environment for AWS CDK. Replace {AWS_ACCOUNT_ID} and {AWS_REGION} with corresponding values first:

cdk bootstrap aws://{AWS_ACCOUNT_ID}/{AWS_REGION}

For more information about bootstrapping, refer to the documentation.

The last step to prepare your environment is to enable CodeWhisperer on your IDE. See Setting up CodeWhisperer for VS Code or Setting up Amazon CodeWhisperer for JetBrains to learn how to do that, depending on which IDE you’re using.

Image download

Let’s get started by implementing the first Lambda function, which is responsible for downloading an image from the provided URL and storing that image in an S3 bucket. Open the get_save_image.py file from the python/api/runtime/ directory. This file contains an empty Lambda function handler and the needed inputs parameters to integrate this Lambda function.

  • url is the URL of the input image provided by the user,
  • name is the name of the image provided by the user, and
  • S3_BUCKET is the S3 bucket name defined by our application infrastructure.

Write a comment in natural language that describes the required functionality, for example:

# Function to get a file from url

To trigger CodeWhisperer, hit the Enter key after entering the comment and wait for a code suggestion. If you want to manually trigger CodeWhisperer, then you can hit Option + C on MacOS or Alt + C on Windows. You can browse through multiple suggestions (if available) with the arrow keys. Accept a code suggestion by pressing Tab. Discard a suggestion by pressing Esc or typing a character.

For more information on how to work with CodeWhisperer, see Working with CodeWhisperer in VS Code or Working with Amazon CodeWhisperer from JetBrains.

You should get a suggested implementation of a function that downloads a file using a specified URL. The following image shows an example of the code snippet that CodeWhisperer suggests:

Screenshot of the code generated by CodeWhisperer on VS Code. It has a function called get_file_from_url with the implementation suggestion to download a file using the requests lib

Figure 2. Screenshot of the code generated by CodeWhisperer on VS Code. It has a function called get_file_from_url with the implementation suggestion to download a file using the requests lib.

Be aware that CodeWhisperer uses artificial intelligence (AI) to provide code recommendations, and that this is non-deterministic. The result you get in your IDE may be different from the one on the image above. If needed, fine-tune the code, as CodeWhisperer generates the core logic, but you might want to customize the details depending on your requirements.

Let’s try another action, this time to upload the image to an S3 bucket:

# Function to upload image to S3

As a result, CodeWhisperer generates a code snippet similar to the following one:

Screenshot of the code generated by CodeWhisperer on VS Code. It has a function called upload_image with the implementation suggestion to download a file using the requests lib and upload it to S3 using the S3 client

Figure 3. Screenshot of the code generated by CodeWhisperer on VS Code. It has a function called upload_image with the implementation suggestion to download a file using the requests lib and upload it to S3 using the S3 client.

Now that you have the functions with the functionalities to download an image from the web and upload it to an S3 bucket, you can wire up both functions in the Lambda handler function by calling each function with the correct inputs.

Image recognition

Now let’s implement the Lambda function responsible for sending the image to Amazon Rekognition for processing, storing the results in a DynamoDB table, and sending a message with those results as JSON to a second Amazon SNS topic. Open the image_recognition.py file from the python/recognition/runtime/ directory. This file contains an empty Lambda and the needed inputs parameters to integrate this Lambda function.

  • queue_url is the URL of the Amazon SQS queue to which this Lambda function is subscribed,
  • table_name is the name of the DynamoDB table, and
  • topic_arn is the ARN of the Amazon SNS topic to which this Lambda function is published.

Using CodeWhisperer, implement the business logic of the next Lambda function as you did in the previous section. For example, to detect the labels from an image using Amazon Rekognition, write the following comment:

# Detect labels from image with Rekognition

And as a result, CodeWhisperer should give you a code snippet similar to the one in the following image:

Screenshot of the code generated by CodeWhisperer on VS Code. It has a function called detect_labels with the implementation suggestion to use the Rekognition SDK to detect labels on the given image

Figure 4. Screenshot of the code generated by CodeWhisperer on VS Code. It has a function called detect_labels with the implementation suggestion to use the Rekognition SDK to detect labels on the given image.

You can continue generating the other functions that you need to fully implement the business logic of your Lambda function. Here are some examples that you can use:

  • # Save labels to DynamoDB
  • # Publish item to SNS
  • # Delete message from SQS

Following the same approach, open the list_images.py file from the python/recognition/runtime/ directory to implement the logic to list all of the labels from the DynamoDB table. As you did previously, type a comment in plain English:

# Function to list all items from a DynamoDB table

Other frequently used code

Interacting with AWS isn’t the only way that you can leverage CodeWhisperer. You can use it to implement repetitive tasks, such as creating unit tests and converting message formats, or to implement algorithms like sorting and string matching and parsing. The last Lambda function that we’ll implement as part of this post is to convert a JSON payload received from Amazon SQS to XML. Then, we’ll POST this XML to an HTTP endpoint.

Open the send_email.py file from the python/integration/runtime/ directory. This file contains an empty Lambda function handler. An event is a JSON-formatted document that contains data for a Lambda function to process. Type a comment with your intent to get the code snippet:

# Transform json to xml

As CodeWhisperer uses the context of your files to generate code, depending on the imports that you have on your file, you’ll get an implementation such as the one in the following image:

Screenshot of the code generated by CodeWhisperer on VS Code. It has a function called json_to_xml with the implementation suggestion to transform JSON payload into XML payload

Figure 5. Screenshot of the code generated by CodeWhisperer on VS Code. It has a function called json_to_xml with the implementation suggestion to transform JSON payload into XML payload.

Repeat the same process with a comment such as # Send XML string with HTTP POST to get the last function implementation. Note that the email server isn’t part of this implementation. You can mock it, or simply ignore this HTTP POST step. Lastly, wire up both functions in the Lambda handler function by calling each function with the correct inputs.

Deploy and test the application

To deploy the application, run the command cdk deploy --all. You should get a confirmation message, and after a few minutes your application will be up and running on your AWS account. As outputs, the APIStack and RekognitionStack will print the API Gateway endpoint URLs. It will look similar to this example:

Outputs:
...
APIStack.RESTAPIEndpoint01234567 = https://examp1eid0.execute-
api.{your-region}.amazonaws.com/prod/
  1. The first endpoint expects two string parameters: url (the image file URL to download) and name (the target file name that will be stored on the S3 bucket). Use any image URL you like, but remember that you must encode an image URL before passing it as a query string parameter to escape the special characters. Use an online URL encoder of your choice for that. Then, use the curl command to invoke the API Gateway endpoint:
curl -X GET 'https://examp1eid0.execute-api.eu-east-
2.amazonaws.com/prod?url={encoded-image-URL}&amp;name={file-name}'

Replace {encoded-image-URL} and {file-name} with the corresponding values. Also, make sure that you use the correct API endpoint that you’ve noted from the AWS CDK deploy command output as mentioned above.

  1. It will take a few seconds for the processing to happen in the background. Once it’s ready, see what has been stored in the DynamoDB table by invoking the List Images API (make sure that you use the correct URL from the output of your deployed AWS CDK stack):
curl -X GET 'https://examp1eid7.execute-api.eu-east-2.amazonaws.com/prod'

After you’re done, to avoid unexpected charges to your account, make sure that you clean up your AWS CDK stacks. Use the cdk destroy command to delete the stacks.

Conclusion

In this post, we’ve seen how to get a significant productivity boost with the help of ML. With that, as a developer, you can stay focused on your IDE and reduce the time that you spend searching online for code snippets that are relevant for your use case. Writing comments in natural language, you get context-based snippets to implement full-fledged applications. In addition, CodeWhisperer comes with a mechanism called reference tracker, which detects whether a code recommendation might be similar to particular CodeWhisperer training data. The reference tracker lets you easily find and review that reference code and see how it’s used in the context of another project. Lastly, CodeWhisperer provides the ability to run scans on your code (generated by CodeWhisperer as well as written by you) to detect security vulnerabilities.

During the preview period, CodeWhisperer is available to all developers across the world for free. Get started with the free preview on JetBrains, VS Code or AWS Cloud9.

About the author:

Rafael Ramos

Rafael is a Solutions Architect at AWS, where he helps ISVs on their journey to the cloud. He spent over 13 years working as a software developer, and is passionate about DevOps and serverless. Outside of work, he enjoys playing tabletop RPG, cooking and running marathons.

Caroline Gluck

Caroline is an AWS Cloud application architect based in New York City, where she helps customers design and build cloud native data science applications. Caroline is a builder at heart, with a passion for serverless architecture and machine learning. In her spare time, she enjoys traveling, cooking, and spending time with family and friends.

Jason Varghese

Jason is a Senior Solutions Architect at AWS guiding enterprise customers on their cloud migration and modernization journeys. He has served in multiple engineering leadership roles and has over 20 years of experience architecting, designing and building scalable software solutions. Jason holds a bachelor’s degree in computer engineering from the University of Oklahoma and an MBA from the University of Central Oklahoma.

Dmitry Balabanov

Dmitry is a Solutions Architect with AWS where he focuses on building reusable assets for customers across multiple industries. With over 15 years of experience in designing, building, and maintaining applications, he still loves learning new things. When not at work, he enjoys paragliding and mountain trekking.

Friday Squid Blogging: Grounded Fishing Boat Carrying 16,000 Pounds of Squid

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/friday-squid-blogging-grounded-fishing-boat-carrying-16000-pounds-of-squid.html

Rough seas are hampering efforts to salvage the boat:

The Speranza Marie, carrying 16,000 pounds of squid and some 1,000 gallons of diesel fuel, hit the shoreline near Chinese Harbor at about 2 a.m. on Dec. 15.

Six crew members were on board, and all were rescued without injury by another fishing boat.

[…]

However, large swells caused by the recent storm caused the Speranza Marie to pull loose from it anchored position and drift about 100 yards from from its original grounded location in Chinese Harbor, according to the Coast Guard.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Recovering Smartphone Voice from the Accelerometer

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/recovering-smartphone-voice-from-the-accelerometer.html

Yet another smartphone side-channel attack: “EarSpy: Spying Caller Speech and Identity through Tiny Vibrations of Smartphone Ear Speakers“:

Abstract: Eavesdropping from the user’s smartphone is a well-known threat to the user’s safety and privacy. Existing studies show that loudspeaker reverberation can inject speech into motion sensor readings, leading to speech eavesdropping. While more devastating attacks on ear speakers, which produce much smaller scale vibrations, were believed impossible to eavesdrop with zero-permission motion sensors. In this work, we revisit this important line of reach. We explore recent trends in smartphone manufacturers that include extra/powerful speakers in place of small ear speakers, and demonstrate the feasibility of using motion sensors to capture such tiny speech vibrations. We investigate the impacts of these new ear speakers on built-in motion sensors and examine the potential to elicit private speech information from the minute vibrations. Our designed system EarSpy can successfully detect word regions, time, and frequency domain features and generate a spectrogram for each word region. We train and test the extracted data using classical machine learning algorithms and convolutional neural networks. We found up to 98.66% accuracy in gender detection, 92.6% detection in speaker detection, and 56.42% detection in digit detection (which is 5X more significant than the random selection (10%)). Our result unveils the potential threat of eavesdropping on phone conversations from ear speakers using motion sensors.

It’s not great, but it’s an impressive start.

Arresting IT Administrators

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/arresting-it-administrators.html

This is one way of ensuring that IT keeps up with patches:

Albanian prosecutors on Wednesday asked for the house arrest of five public employees they blame for not protecting the country from a cyberattack by alleged Iranian hackers.

Prosecutors said the five IT officials of the public administration department had failed to check the security of the system and update it with the most recent antivirus software.

The next step would be to arrest managers at software companies for not releasing patches fast enough. And maybe programmers for writing buggy code. I don’t know where this line of thinking ends.

LastPass Breach

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/lastpass-breach.html

Last August, LastPass reported a security breach, saying that no customer information—or passwords—were compromised. Turns out the full story is worse:

While no customer data was accessed during the August 2022 incident, some source code and technical information were stolen from our development environment and used to target another employee, obtaining credentials and keys which were used to access and decrypt some storage volumes within the cloud-based storage service.

[…]

To date, we have determined that once the cloud storage access key and dual storage container decryption keys were obtained, the threat actor copied information from backup that contained basic customer account information and related metadata including company names, end-user names, billing addresses, email addresses, telephone numbers, and the IP addresses from which customers were accessing the LastPass service.

The threat actor was also able to copy a backup of customer vault data from the encrypted storage container which is stored in a proprietary binary format that contains both unencrypted data, such as website URLs, as well as fully-encrypted sensitive fields such as website usernames and passwords, secure notes, and form-filled data.

That’s bad. It’s not an epic disaster, though.

These encrypted fields remain secured with 256-bit AES encryption and can only be decrypted with a unique encryption key derived from each user’s master password using our Zero Knowledge architecture. As a reminder, the master password is never known to LastPass and is not stored or maintained by LastPass.

So, according to the company, if you chose a strong master password—here’s my advice on how to do it—your passwords are safe. That is, you are secure as long as your password is resilient to a brute-force attack. (That they lost customer data is another story….)

Fair enough, as far as it goes. My guess is that many LastPass users do not have strong master passwords, even though the compromise of your encrypted password file should be part of your threat model. But, even so, note this unverified tweet:

I think the situation at @LastPass may be worse than they are letting on. On Sunday the 18th, four of my wallets were compromised. The losses are not significant. Their seeds were kept, encrypted, in my lastpass vault, behind a 16 character password using all character types.

If that’s true, it means that LastPass has some backdoor—possibly unintentional—into the password databases that the hackers are accessing. (Or that @Cryptopathic’s “16 character password using all character types” is something like “P@ssw0rdP@ssw0rd.”)

My guess is that we’ll learn more during the coming days. But this should serve as a cautionary tale for anyone who is using the cloud: the cloud is another name for “someone else’s computer,” and you need to understand how much or how little you trust that computer.

If you’re changing password managers, look at my own Password Safe. Its main downside is that you can’t synch between devices, but that’s because I don’t use the cloud for anything.

News articles. Slashdot thread.

EDITED TO ADD: People choose lousy master passwords.

Friday Squid Blogging: Injured Giant Squid and Paddleboarder

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/friday-squid-blogging-injured-giant-squid-and-paddleboarder.html

Here’s a video—I don’t know where it’s from—of an injured juvenile male giant squid grabbing on to a paddleboard.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Enabling load-balancing of non-HTTP(s) traffic on AWS Wavelength

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/enabling-load-balancing-of-non-https-traffic-on-aws-wavelength/

This blog post is written by Jack Chen, Telco Solutions Architect, and Robert Belson, Developer Advocate.

AWS Wavelength embeds AWS compute and storage services within 5G networks, providing mobile edge computing infrastructure for developing, deploying, and scaling ultra-low-latency applications. AWS recently introduced support for Application Load Balancer (ALB) in AWS Wavelength zones. Although ALB addresses Layer-7 load balancing use cases, some low latency applications that get deployed in AWS Wavelength Zones rely on UDP-based protocols, such as QUIC, WebRTC, and SRT, which can’t be load-balanced by Layer-7 Load Balancers. In this post, we’ll review popular load-balancing patterns on AWS Wavelength, including a proposed architecture demonstrating how DNS-based load balancing can address customer requirements for load-balancing non-HTTP(s) traffic across multiple Amazon Elastic Compute Cloud (Amazon EC2) instances. This solution also builds a foundation for automatic scale-up and scale-down capabilities for workloads running in an AWS Wavelength Zone.

Load balancing use cases in AWS Wavelength

In the AWS Regions, customers looking to deploy highly-available edge applications often consider Amazon Elastic Load Balancing (Amazon ELB) as an approach to automatically distribute incoming application traffic across multiple targets in one or more Availability Zones (AZs). However, at the time of this publication, AWS-managed Network Load Balancer (NLB) isn’t supported in AWS Wavelength Zones and ALB is being rolled out to all AWS Wavelength Zones globally. As a result, this post will seek to document general architectural guidance for load balancing solutions on AWS Wavelength.

As one of the most prominent AWS Wavelength use cases, highly-immersive video streaming over UDP using protocols such as WebRTC at scale often require a load balancing solution to accommodate surges in traffic, either due to live events or general customer access patterns. These use cases, relying on Layer-4 traffic, can’t be load-balanced from a Layer-7 ALB. Instead, Layer-4 load balancing is needed.

To date, two infrastructure deployments involving Layer-4 load balancers are most often seen:

  • Amazon EC2-based deployments: Often the environment of choice for earlier-stage enterprises and ISVs, a fleet of EC2 instances will leverage a load balancer for high-throughput use cases, such as video streaming, data analytics, or Industrial IoT (IIoT) applications
  • Amazon EKS deployments: Customers looking to optimize performance and cost efficiency of their infrastructure can leverage containerized deployments at the edge to manage their AWS Wavelength Zone applications. In turn, external load balancers could be configured to point to exposed services via NodePort objects. Furthermore, a more popular choice might be to leverage the AWS Load Balancer Controller to provision an ALB when you create a Kubernetes Ingress.

Regardless of deployment type, the following design constraints must be considered:

  • Target registration: For load balancing solutions not managed by AWS, seamless solutions to load balancer target registration must be managed by the customer. As one potential solution, visit a recent HAProxyConf presentation, Practical Advice for Load Balancing at the Network Edge.
  • Edge Discovery: Although DNS records can be populated into Amazon Route 53 for each carrier-facing endpoint, DNS won’t deterministically route mobile clients to the most optimal mobile endpoint. When available, edge discovery services are required to most effectively route mobile clients to the lowest latency endpoint.
  • Cross-zone load balancing: Given the hub-and-spoke design of AWS Wavelength, customer-managed load balancers should proxy traffic only to that AWS Wavelength Zone.

Solution overview – Amazon EC2

In this solution, we’ll present a solution for a highly-available load balancing solution in a single AWS Wavelength Zone for an Amazon EC2-based deployment. In a separate post, we’ll cover the needed configurations for the AWS Load Balancer Controller in AWS Wavelength for Amazon Elastic Kubernetes Service (Amazon EKS) clusters.

The proposed solution introduces DNS-based load balancing, a technique to abstract away the complexity of intelligent load-balancing software and allow your Domain Name System (DNS) resolvers to distribute traffic (equally, or in a weighted distribution) to your set of endpoints.

Our solution leverages the weighted routing policy in Route 53 to resolve inbound DNS queries to multiple EC2 instances running within an AWS Wavelength zone. As EC2 instances for a given workload get deployed in an AWS Wavelength zone, Carrier IP addresses can be assigned to the network interfaces at launch.

Through this solution, Carrier IP addresses attached to AWS Wavelength instances are automatically added as DNS records for the customer-provided public hosted zone.

To determine how Route 53 responds to queries, given an arbitrary number of records of a public hosted zone, Route53 offers numerous routing policies:

Simple routing policy – In the event that you must route traffic to a single resource in an AWS Wavelength Zone, simple routing can be used. A single record can contain multiple IP addresses, but Route 53 returns the values in a random order to the client.

Weighted routing policy – To route traffic more deterministically using a set of proportions that you specify, this policy can be selected. For example, if you would like Carrier IP A to receive 50% of the traffic and Carrier IP B to receive 50% of the traffic, we’ll create two individual A records (one for each Carrier IP) with a weight of 50 and 50, respectively. Learn more about Route 53 routing policies by visiting the Route 53 Developer Guide.

The proposed solution leverages weighted routing policy in Route 53 DNS to route traffic to multiple EC2 instances running within an AWS Wavelength zone.

Reference architecture

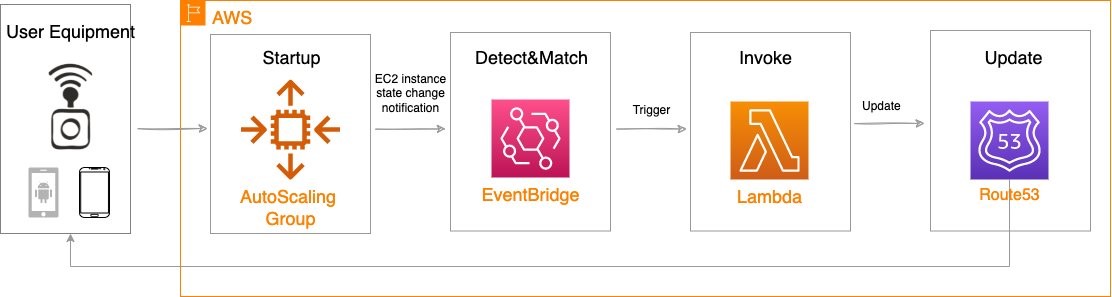
The following diagram illustrates the load-balancing component of the solution, where EC2 instances in an AWS Wavelength zone are assigned Carrier IP addresses. A weighted DNS record for a host (e.g., www.example.com) is updated with Carrier IP addresses.

DNS-based load balancing

When a device makes a DNS query, it will be returned to one of the Carrier IP addresses associated with the given domain name. With a large number of devices, we expect a fair distribution of load across all EC2 instances in the resource pool. Given the highly ephemeral mobile edge environments, it’s likely that Carrier IPs could frequently be allocated to accommodate a workload and released shortly thereafter. However, this unpredictable behavior could yield stale DNS records, resulting in a “blackhole” – routes to endpoints that no longer exist.

Time-To-Live (TTL) is a DNS attribute that specifies the amount of time, in seconds, that you want DNS recursive resolvers to cache information about this record.

In our example, we should set to 30 seconds to force DNS resolvers to retrieve the latest records from the authoritative nameservers and minimize stale DNS responses. However, a lower TTL has a direct impact on cost, as a result of increased number of calls from recursive resolvers to Route53 to constantly retrieve the latest records.

The core components of the solution are as follows:

Alongside the services above in the AWS Wavelength Zone, the following services are also leveraged in the AWS Region:

  • AWS Lambda – a serverless event-driven function that makes API calls to the Route 53 service to update DNS records.
  • Amazon EventBridge– a serverless event bus that reacts to EC2 instance lifecycle events and invokes the Lambda function to make DNS updates.
  • Route 53– cloud DNS service with a domain record pointing to AWS Wavelength-hosted resources.

In this post, we intentionally leave the specific load balancing software solution up to the customer. Customers can leverage various popular load balancers available on the AWS Marketplace, such as HAProxy and NGINX. To focus our solution on the auto-registration of DNS records to create functional load balancing, this solution is designed to support stateless workloads only. To support stateful workloads, sticky sessions – a process in which routes requests to the same target in a target group – must be configured by the underlying load balancer solution and are outside of the scope of what DNS can provide natively.

Automation overview

Using the aforementioned components, we can implement the following workflow automation:

Event-driven Auto Scaling Workflow

Amazon CloudWatch alarm can trigger the Auto Scaling group Scale out or Scale in event by adding or removing EC2 instances. Eventbridge will detect the EC2 instance state change event and invoke the Lambda function. This function will update the DNS record in Route53 by either adding (scale out) or deleting (scale in) a weighted A record associated with the EC2 instance changing state.

Configuration of the automatic auto scaling policy is out of the scope of this post. There are many auto scaling triggers that you can consider using, based on predefined and custom metrics such as memory utilization. For the demo purposes, we will be leveraging manual auto scaling.

In addition to the core components that were already described, our solution also utilizes AWS Identity and Access Management (IAM) policies and CloudWatch. Both services are key components to building AWS Well-Architected solutions on AWS. We also use AWS Systems Manager Parameter Store to keep track of user input parameters. The deployment of the solution is automated via AWS CloudFormation templates. The Lambda function provided should be uploaded to an AWS Simple Storage Service (Amazon S3) bucket.

Amazon Virtual Private Cloud (Amazon VPC), subnets, Carrier Gateway, and Route Tables are foundational building blocks for AWS-based networking infrastructure. In our deployment, we are creating a new VPC, one subnet in an AWS Wavelength zone of your choice, a Carrier Gateway, and updating the route table for this subnet to point the default route to the Carrier Gateway.

Wavelength VPC architecture.

Deployment prerequisites

The following are prerequisites to deploy the described solution in your account:

  • Access to an AWS Wavelength zone. If your account is not allow-listed to use AWS Wavelength zones, then opt-in to AWS Wavelength zones here.
  • Public DNS Hosted Zone hosted in Route 53. You must have access to a registered public domain to deploy this solution. The zone for this domain should be hosted in the same account where you plan to deploy AWS Wavelength workloads.
    If you don’t have a public domain, then you can register a new one. Note that there will be a service charge for the domain registration.
  • Amazon S3 bucket. For the Lambda function that updates DNS records in Route 53, store the source code as a .zip file in an Amazon S3 bucket.
  • Amazon EC2 Key pair. You can use an existing Key pair for the deployment. If you don’t have a KeyPair in the region where you plan to deploy this solution, then create one by following these instructions.
  • 4G or 5G-connected device. Although the infrastructure can be deployed independent of the underlying connected devices, testing the connectivity will require a mobile device on one of the Wavelength partner’s networks. View the complete list of Telecommunications providers and Wavelength Zone locations to learn more.

Conclusion

In this post, we demonstrated how to implement DNS-based load balancing for workloads running in an AWS Wavelength zone. We deployed the solution that used the EventBridge Rule and the Lambda function to update DNS records hosted by Route53. If you want to learn more about AWS Wavelength, subscribe to AWS Compute Blog channel here.

Critical Microsoft Code-Execution Vulnerability

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/critical-microsoft-code-execution-vulnerability.html

A critical code-execution vulnerability in Microsoft Windows was patched in September. It seems that researchers just realized how serious it was (and is):

Like EternalBlue, CVE-2022-37958, as the latest vulnerability is tracked, allows attackers to execute malicious code with no authentication required. Also, like EternalBlue, it’s wormable, meaning that a single exploit can trigger a chain reaction of self-replicating follow-on exploits on other vulnerable systems. The wormability of EternalBlue allowed WannaCry and several other attacks to spread across the world in a matter of minutes with no user interaction required.

But unlike EternalBlue, which could be exploited when using only the SMB, or server message block, a protocol for file and printer sharing and similar network activities, this latest vulnerability is present in a much broader range of network protocols, giving attackers more flexibility than they had when exploiting the older vulnerability.

[…]

Microsoft fixed CVE-2022-37958 in September during its monthly Patch Tuesday rollout of security fixes. At the time, however, Microsoft researchers believed the vulnerability allowed only the disclosure of potentially sensitive information. As such, Microsoft gave the vulnerability a designation of “important.” In the routine course of analyzing vulnerabilities after they’re patched, Palmiotti discovered it allowed for remote code execution in much the way EternalBlue did. Last week, Microsoft revised the designation to critical and gave it a severity rating of 8.1, the same given to EternalBlue.

Ukraine Intercepting Russian Soldiers’ Cell Phone Calls

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/ukraine-intercepting-russian-soldiers-cell-phone-calls.html

They’re using commercial phones, which go through the Ukrainian telecom network:

“You still have a lot of soldiers bringing cellphones to the frontline who want to talk to their families and they are either being intercepted as they go through a Ukrainian telecommunications provider or intercepted over the air,” said Alperovitch. “That doesn’t pose too much difficulty for the Ukrainian security services.”

[…]

“Security has always been a mess, both in the army and among defence officials,” the source said. “For example, in 2013 they tried to get all the staff at the ministry of defence to replace our iPhones with Russian-made Yoto smartphones.

“But everyone just kept using the iPhone as a second mobile because it was much better. We would just keep the iPhone in the car’s glove compartment for when we got back from work. In the end, the ministry gave up and stopped caring. If the top doesn’t take security very seriously, how can you expect any discipline in the regular army?”

This isn’t a new problem and it isn’t a Russian problem. Here’s a more general article on the problem from 2020.

Trojaned Windows Installer Targets Ukraine

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/trojaned-windows-installer-targets-ukraine.html

Mandiant is reporting on a trojaned Windows installer that targets Ukrainian users. The installer was left on various torrent sites, presumably ensnaring people downloading pirated copies of the operating system:

Mandiant uncovered a socially engineered supply chain operation focused on Ukrainian government entities that leveraged trojanized ISO files masquerading as legitimate Windows 10 Operating System installers. The trojanized ISOs were hosted on Ukrainian- and Russian-language torrent file sharing sites. Upon installation of the compromised software, the malware gathers information on the compromised system and exfiltrates it. At a subset of victims, additional tools are deployed to enable further intelligence gathering. In some instances, we discovered additional payloads that were likely deployed following initial reconnaissance including the STOWAWAY, BEACON, and SPAREPART backdoors.

One obvious solution would be for Microsoft to give the Ukrainians Windows licenses, so they don’t have to get their software from sketchy torrent sites.

How to Surrender to a Drone

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/how-to-surrender-to-a-drone.html

The Ukrainian army has released an instructional video explaining how Russian soldiers should surrender to a drone:

“Seeing the drone in the field of view, make eye contact with it,” the video instructs. Soldiers should then raise their arms and signal they’re ready to follow.

After that the drone will move up and down a few meters, before heading off at walking pace in the direction of the nearest representatives of Ukraine’s army, it says.

The video also warns that the drone’s battery may run low, in which case it will head back to base and the soldiers should stay put and await a fresh one.

That one, too, should be met with eye contact and arms raised, it says.

Incredible.

Friday Squid Blogging: Squid in Concert

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/12/friday-squid-blogging-squid-in-concert.html

Squid is performing a concert in London in February.

If you don’t know what their music is like, try this or this or this.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.