Improving the WAF with Machine Learning

Post Syndicated from Daniele Molteni original https://blog.cloudflare.com/waf-ml/
Improving the WAF with Machine Learning

Improving the WAF with Machine Learning

Cloudflare handles 32 million HTTP requests per second and is used by more than 22% of all the websites whose web server is known by W3Techs. Cloudflare is in the unique position of protecting traffic for 1 out of 5 Internet properties which allows it to identify threats as they arise and track how these evolve and mutate.

The Web Application Firewall (WAF) sits at the core of Cloudflare’s security toolbox and  Managed Rules are a key feature of the WAF. They are a collection of rules created by Cloudflare’s analyst team that block requests when they show patterns of known attacks. These managed rules work extremely well for patterns of established attack vectors, as they have been extensively tested to minimize both false negatives (missing an attack) and false positives (finding an attack when there isn’t one). On the downside, managed rules often miss attack variations (also known as bypasses) as static regex-based rules are intrinsically sensitive to signature variations introduced, for example, by fuzzing techniques.

We witnessed this issue when we released protections for log4j. For a few days, after the vulnerability was made public, we had to constantly update the rules to match variations and mutations as attackers tried to bypass the WAF. Moreover, optimizing rules requires significant human intervention, and it usually works only after bypasses have been identified or even exploited, making the protection reactive rather than proactive.

Today we are excited to complement managed rulesets (such as OWASP and Cloudflare Managed) with a new tool aimed at identifying bypasses and malicious payloads without human involvement, and before they are exploited. Customers can now access signals from a machine learning model trained on the good/bad traffic as classified by managed rules and augmented data to provide better protection across a broader range of old and new attacks.

Welcome to our new Machine Learning WAF detection.

The new detection is available in Early Access for Enterprise, Pro and Biz customers. Please join the waitlist if you are interested in trying it out. In the long term, it will be available to the higher tier customers.

Improving the WAF with learning capabilities

The new detection system complements existing managed rulesets by providing three major advantages:

  1. It runs on all of your traffic. Each request is scored based on the likelihood that it contains a SQLi or XSS attack, for example. This enables a new WAF analytics experience that allows you to explore trends and patterns in your overall traffic.
  2. Detection rate improves based on past traffic and feedback. The model is trained on good and bad traffic as categorized by managed rules across all Cloudflare traffic. This allows small sites to get the same level of protection as the largest Internet properties.
  3. A new definition of performance. The machine learning engine identifies bypasses and anomalies before they are exploited or identified by human researchers.

The secret sauce is a combination of innovative machine learning modeling, a vast training dataset built on the attacks we block daily as well as data augmentation techniques, the right evaluation and testing framework based on the behavioral testing principle and cutting-edge engineering that allows us to assess each request with negligible latency.

A new WAF experience

The new detection is based on the paradigm launched with Bot Analytics. Following this approach, each request is evaluated, and a score assigned, regardless of whether we are taking actions on it. Since we score every request, users can visualize how the score evolves over time for the entirety of the traffic directed to their server.
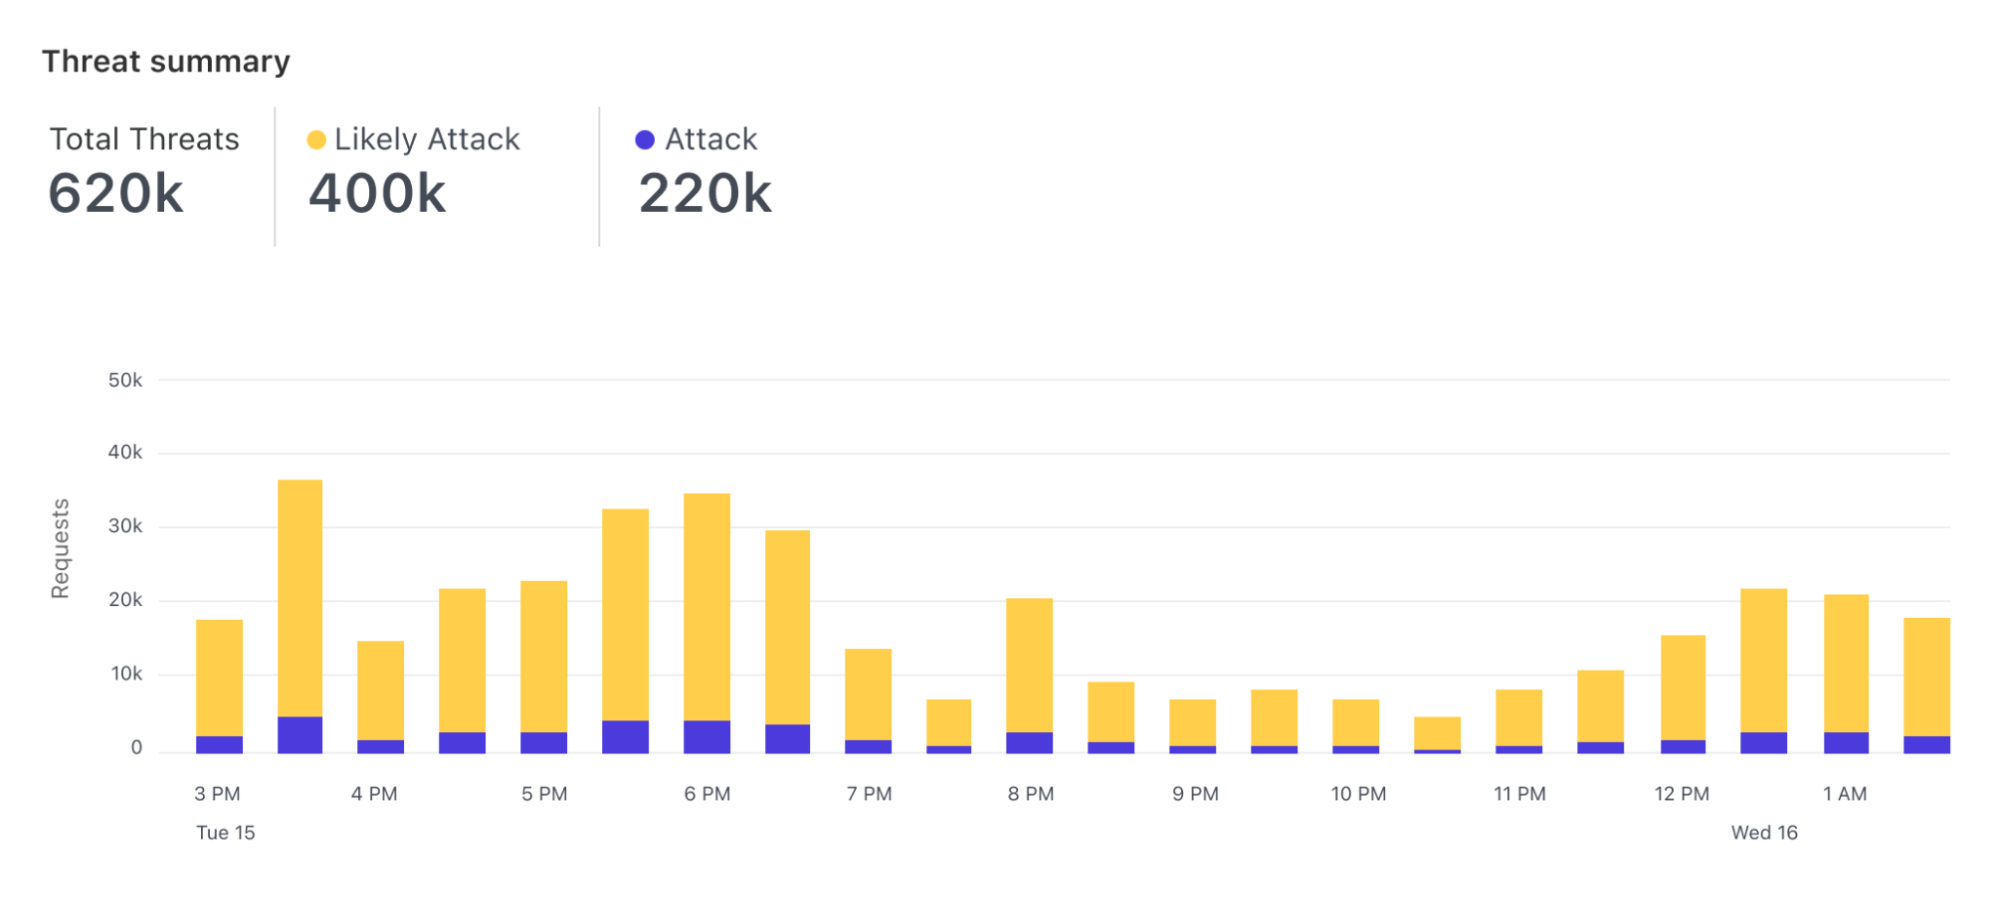
Improving the WAF with Machine Learning

Furthermore, users can visualize the histogram of how requests were scored for a specific attack vector (such as SQLi) and find what score is a good value to separate good from bad traffic.

The actual mitigation is performed with custom WAF rules where the score is used to decide which requests should be blocked. This allows customers to create rules whose logic includes any parameter of the HTTP requests, including the dynamic fields populated by Cloudflare, such as bot scores.
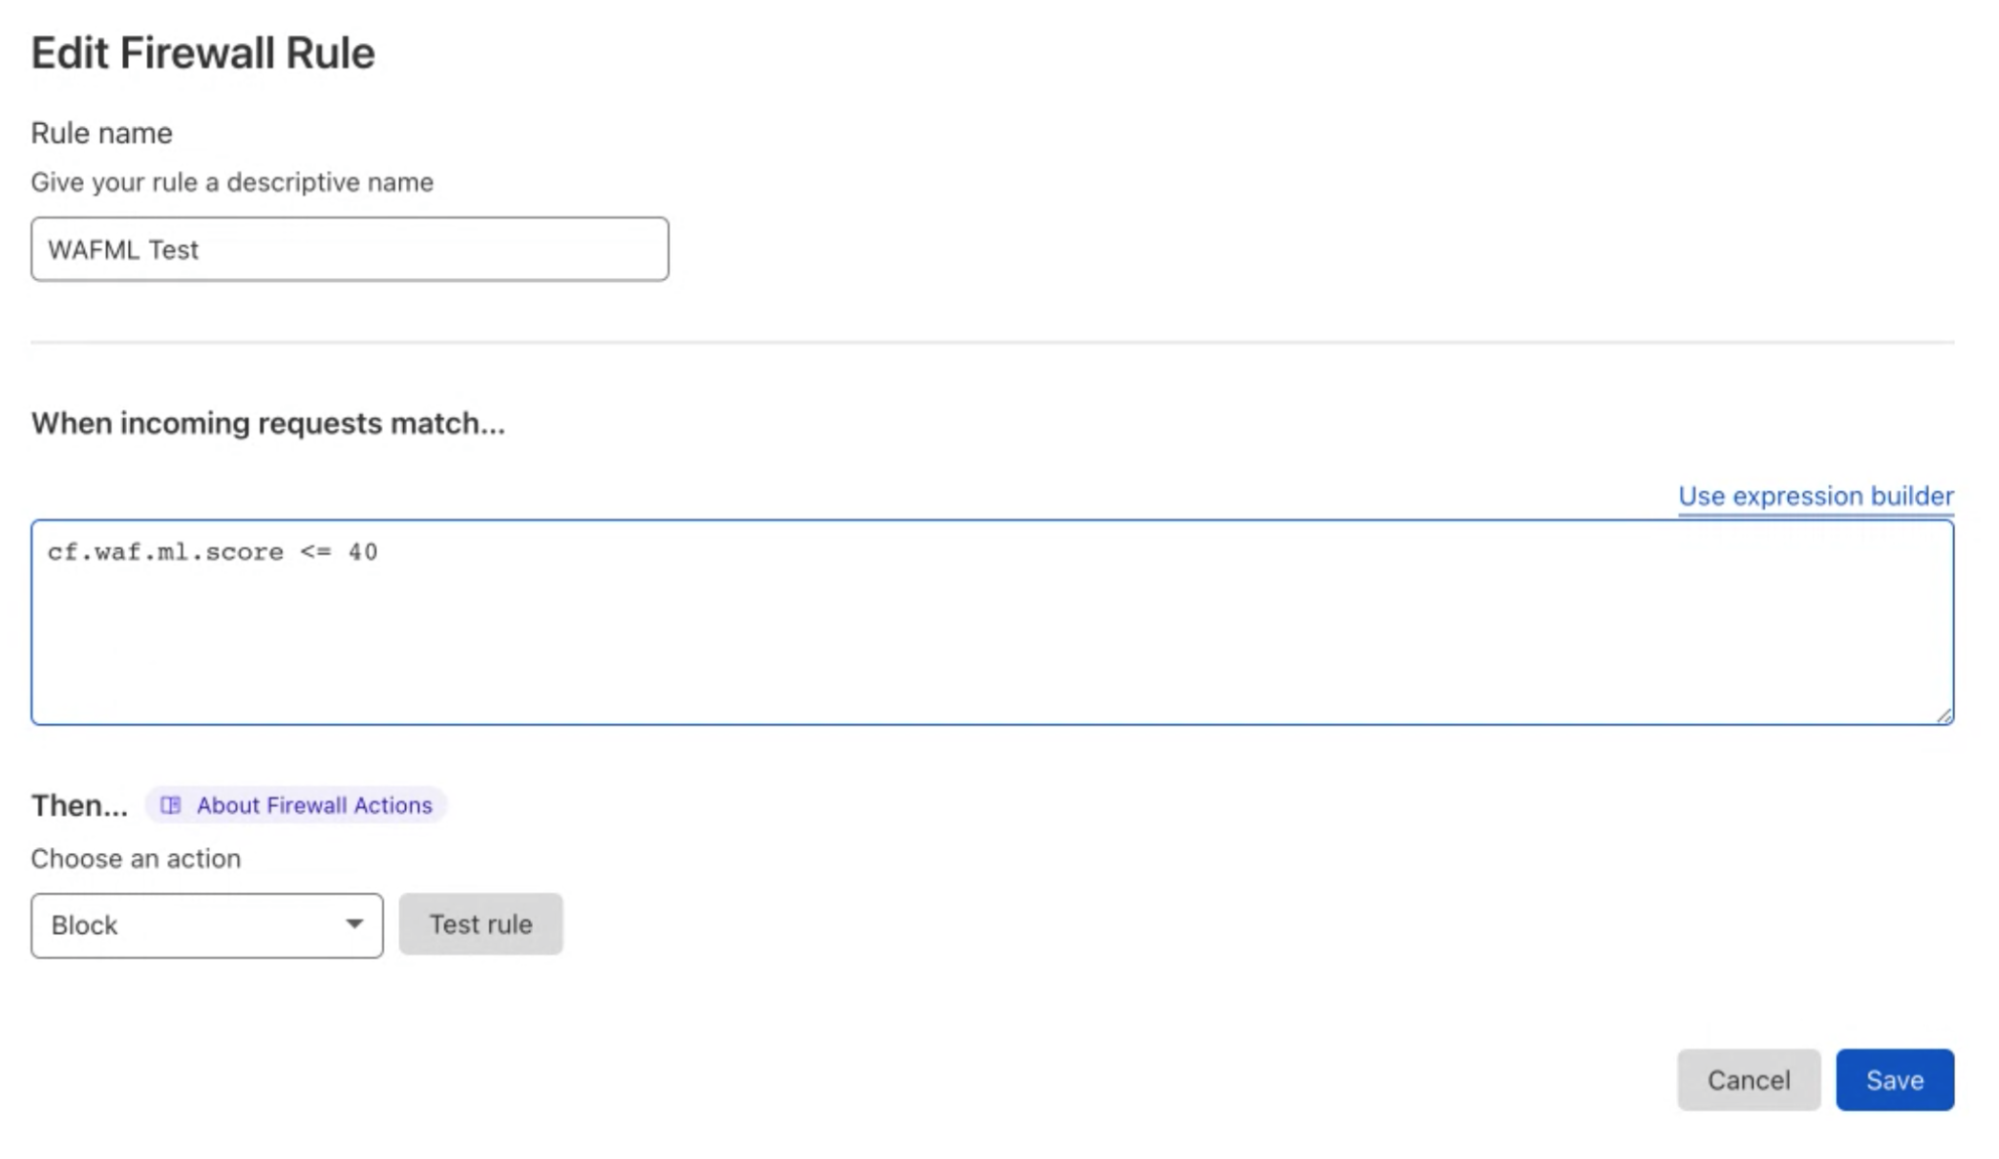
Improving the WAF with Machine Learning

We are now looking at extending this approach to work for the managed rules too (OWASP and Cloudflare Managed). Customers will be able to identify trends and create rules based on patterns that are visible when looking at their overall traffic; rather than creating rules based on trial and error, log traffic to validate them and finally enforce protection.

How does it work?

Machine learning–based detections complement the existing managed rulesets, such as OWASP and Cloudflare Managed. The system is based on models designed to identify variations of attack patterns and anomalies without the direct supervision of researchers or the end user.

As of today, we expose scores for two attack vectors: SQL injection and Cross Site Scripting. Users can create custom WAF/Firewall rules using three separate scores: a total score (cf.waf.ml.score), one for SQLi and one for XSS (cf.waf.ml.score.sqli, cf.waf.ml.score.xss, respectively). The scores can have values between 1 and 99, with 1 being definitely malicious and 99 being valid traffic.
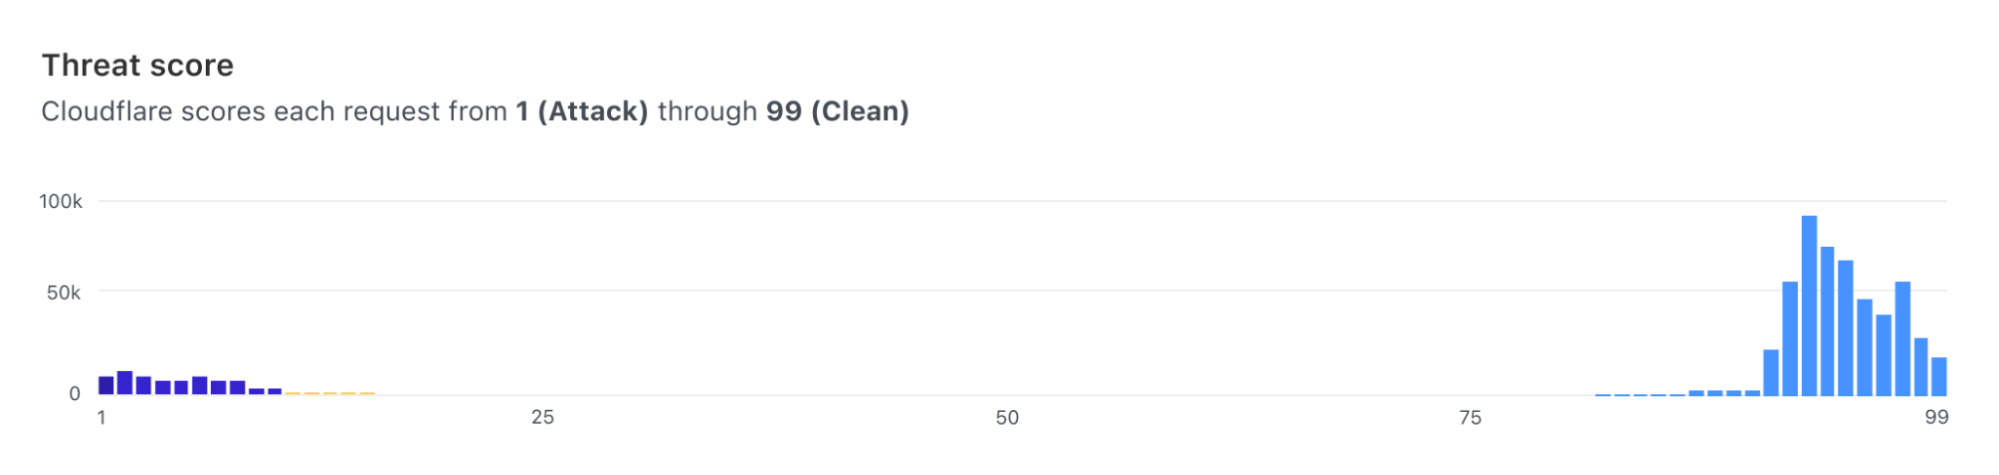
Improving the WAF with Machine Learning

The model is then trained based on traffic classified by the existing WAF rules, and it works on a transformed version of the original request, making it easier to identify fingerprints of attacks.

For each request, the model scores each part of the request independently so that it’s possible to identify where malicious payloads were identified, for example, in the body of the request, the URI or headers.
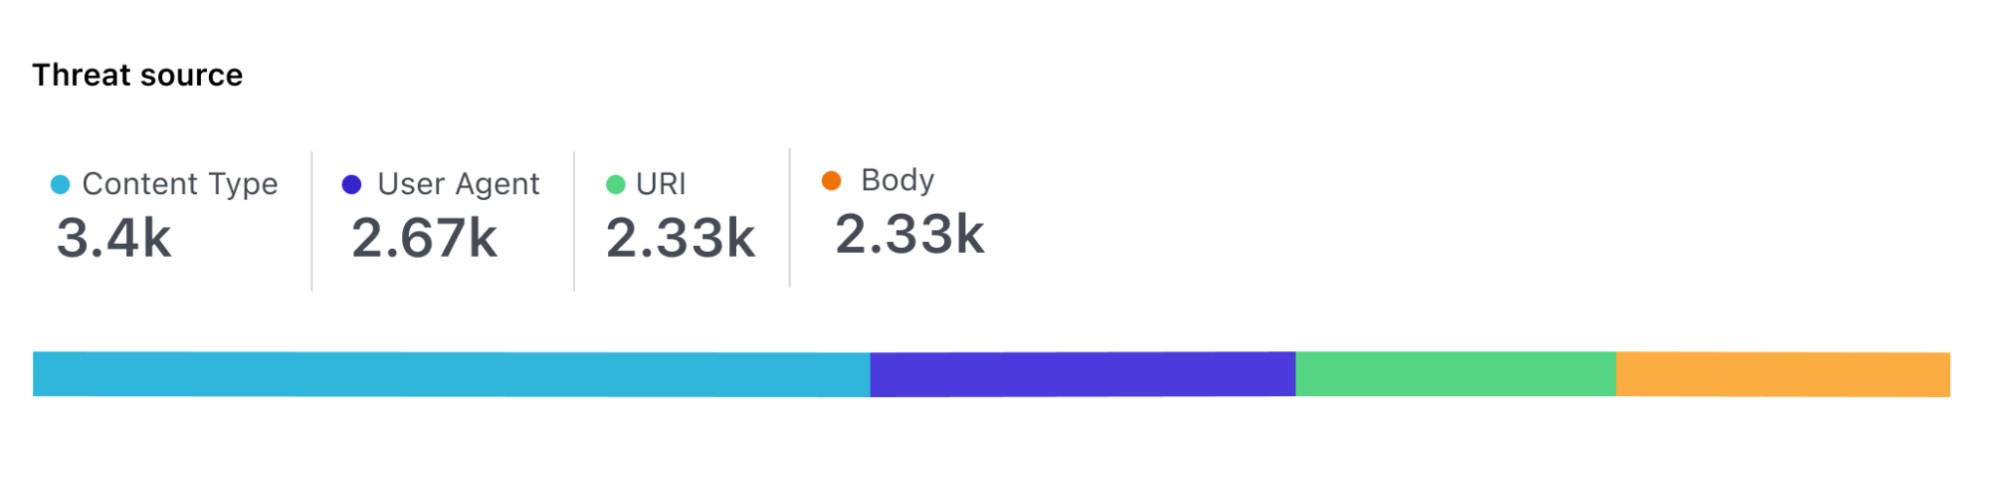
Improving the WAF with Machine Learning

This looks easy on paper, but there are a number of challenges that Cloudflare engineers had to solve to get here. This includes how to build a reliable dataset, scalable data labeling, selecting the right model architecture, and the requirement for executing the categorization on every request processed by Cloudflare’s global network (i.e. 32 million times per seconds).

In the coming weeks, the Engineering team will publish a series of blog posts which will give a better understanding of how the solution works under the hood.

Looking forward

In the next months, we are going to release the new detection engine to customers and collect their feedback on its performance. Long term, we are planning to extend the detection engine to cover all attack vectors already identified by managed rules and use the attacks blocked by the machine learning model to further improve our managed rulesets.
A new WAF experience

Post Syndicated from Zhiyuan Zheng original https://blog.cloudflare.com/new-waf-experience/

A new WAF experience

A new WAF experience

Around three years ago, we brought multiple features into the Firewall tab in our dashboard navigation, with the motivation “to make our products and services intuitive.” With our hard work in expanding capabilities offerings in the past three years, we want to take another opportunity to evaluate the intuitiveness of Cloudflare WAF (Web Application Firewall).

Our customers lead the way to new WAF

The security landscape is moving fast; types of web applications are growing rapidly; and within the industry there are various approaches to what a WAF includes and can offer. Cloudflare not only proxies enterprise applications, but also millions of personal blogs, community sites, and small businesses stores. The diversity of use cases are covered by various products we offer; however, these products are currently scattered and that makes visibility of active protection rules unclear. This pushes us to reflect on how we can best support our customers in getting the most value out of WAF by providing a clearer offering that meets expectations.

A few months ago, we reached out to our customers to answer a simple question: what do you consider to be part of WAF? We employed a range of user research methods including card sorting, tree testing, design evaluation, and surveys to help with this. The results of this research illustrated how our customers think about WAF, what it means to them, and how it supports their use cases. This inspired the product team to expand scope and contemplate what (Web Application) Security means, beyond merely the WAF.

Based on what hundreds of customers told us, our user research and product design teams collaborated with product management to rethink the security experience. We examined our assumptions and assessed the effectiveness of design concepts to create a structure (or information architecture) that reflected our customers’ mental models.

This new structure consolidates firewall rules, managed rules, and rate limiting rules to become a part of WAF. The new WAF strives to be the one-stop shop for web application security as it pertains to differentiating malicious from clean traffic.

As of today, you will see the following changes to our navigation:

  1. Firewall is being renamed to Security.
  2. Under Security, you will now find WAF.
  3. Firewall rules, managed rules, and rate limiting rules will now appear under WAF.

From now on, when we refer to WAF, we will be referring to above three features.

Further, some important updates are coming for these features. Advanced rate limiting rules will be launched as part of Security Week, and every customer will also get a free set of managed rules to protect all traffic from high profile vulnerabilities. And finally, in the next few months, firewall rules will move to the Ruleset Engine, adding more powerful capabilities thanks to the new Ruleset API. Feeling excited?

How customers shaped the future of WAF

Almost 500 customers participated in this user research study that helped us learn about needs and context of use. We employed four research methods, all of which were conducted in an unmoderated manner; this meant people around the world could participate remotely at a time and place of their choosing.

  • Card sorting involved participants grouping navigational elements into categories that made sense to them.
  • Tree testing assessed how well or poorly a proposed navigational structure performed for our target audience.
  • Design evaluation involved a task-based approach to measure effectiveness and utility of design concepts.
  • Survey questions helped us dive deeper into results, as well as painting a picture of our participants.

Results of this four-pronged study informed changes to both WAF and Security that are detailed below.

The new WAF experience

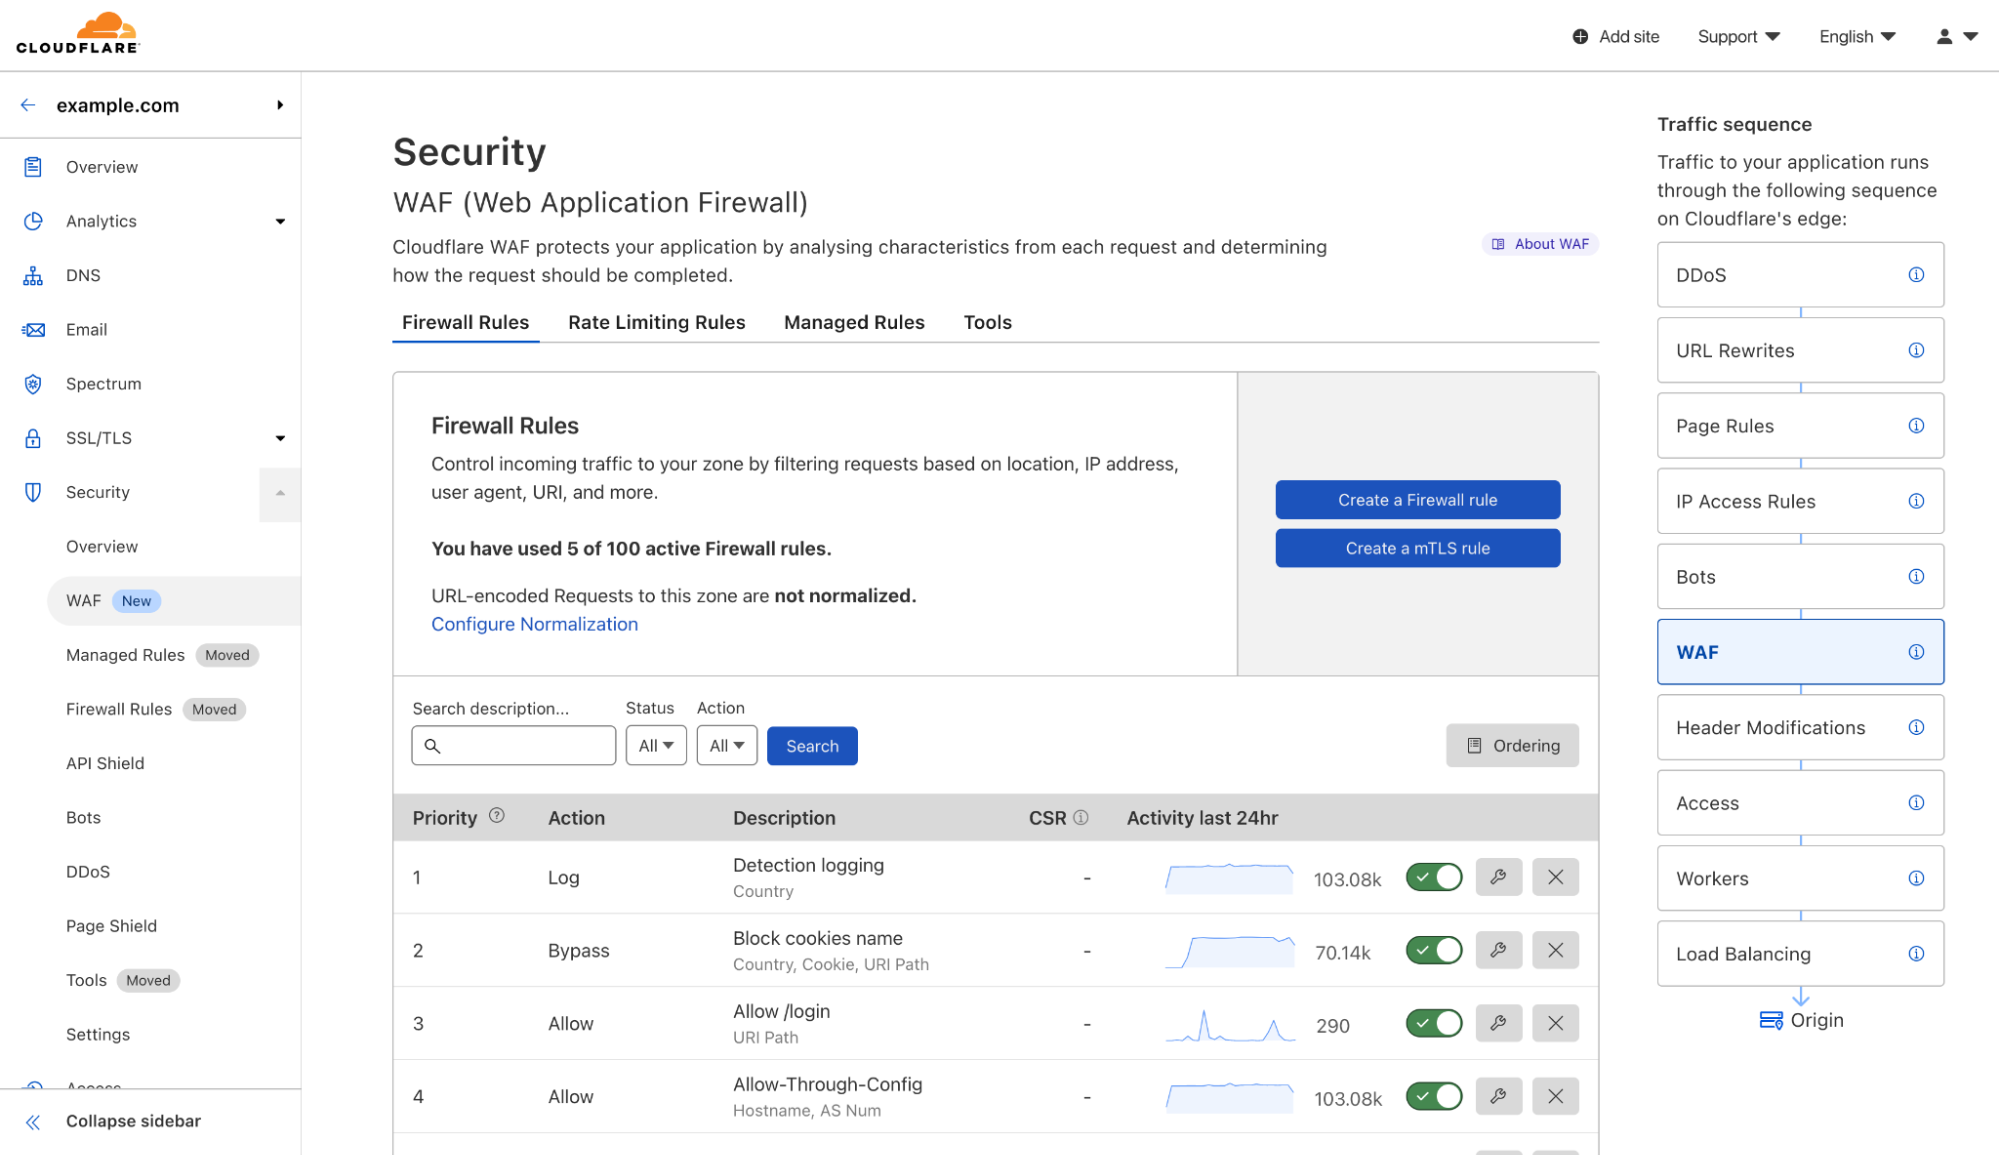
The final result reveals the WAF as part of a broader Security category, which also includes Bots, DDoS, API Shield and Page Shield. This destination enables you to create your rules (a.k.a. firewall rules), deploy Cloudflare managed rules, set rate limit conditions, and includes handy tools to protect your web applications.

All customers across all plans will now see the WAF products organized as below:

A new WAF experience
  1. Firewall rules allow you to create custom, user-defined logic by blocking or allowing traffic that leverages all the components of the HTTP requests and dynamic fields computed by Cloudflare, such as Bot score.
  2. Rate limiting rules include the traditional IP-based product we launched back in 2018 and the newer Advanced Rate Limiting for ENT customers on the Advanced plan (coming soon).
  3. Managed rules allows customers to deploy sets of rules managed by the Cloudflare analyst team. These rulesets include a “Cloudflare Free Managed Ruleset” currently being rolled out for all plans including FREE, as well as Cloudflare Managed, OWASP implementation, and Exposed Credentials Check for all paying plans.
  4. Tools give access to IP Access Rules, Zone Lockdown and User Agent Blocking. Although still actively supported, these products cover specific use cases that can be covered using firewall rules. However, they remain a part of the WAF toolbox for convenience.

Redesigning the WAF experience

Gestalt design principles suggest that “elements which are close in proximity to each other are perceived to share similar functionality or traits.” This principle in addition to the input from our customers informed our design decisions.

After reviewing the responses of the study, we understood the importance of making it easy to find the security products in the Dashboard, and the need to make it clear how particular products were related to or worked together with each other.

Crucially, the page needed to:

  • Display each type of rule we support, i.e. firewall rules, rate limiting rules and managed rules
  • Show the usage amount of each type
  • Give the customer the ability to add a new rule and manage existing rules
  • Allow the customer to reprioritise rules using the existing drag and drop behavior
  • Be flexible enough to accommodate future additions and consolidations of WAF features

We iterated on multiple options, including predominantly vertical page layouts, table based page layouts, and even accordion based page layouts. Each of these options, however, would force us to replicate buttons of similar functionality on the page. With the risk of causing additional confusion, we abandoned these options in favor of a horizontal, tabbed page layout.

How can I get it?

As of today, we are launching this new design of WAF to everyone! In the meantime, we are updating documentation to walk you through how to maximize the power of Cloudflare WAF.

Looking forward

This is a starting point of our journey to make Cloudflare WAF not only powerful but also easy to adapt to your needs. We are evaluating approaches to empower your decision-making process when protecting your web applications. Among growing intel information and more rules creation possibilities, we want to shorten your path from a possible threat detection (such as by security overview) to setting up the right rule to mitigate such threat. Stay tuned!

US Critical Infrastructure Companies Will Have to Report When They Are Hacked

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/03/us-critical-infrastructure-companies-will-have-to-report-when-they-are-hacked.html

This will be law soon:

Companies critical to U.S. national interests will now have to report when they’re hacked or they pay ransomware, according to new rules approved by Congress.

[…]

The reporting requirement legislation was approved by the House and the Senate on Thursday and is expected to be signed into law by President Joe Biden soon. It requires any entity that’s considered part of the nation’s critical infrastructure, which includes the finance, transportation and energy sectors, to report any “substantial cyber incident” to the government within three days and any ransomware payment made within 24 hours.

Even better would be if they had to report it to the public.

AWS Week in Review – March 14, 2022

Post Syndicated from Steve Roberts original https://aws.amazon.com/blogs/aws/aws-week-in-review-march-14-2022/

This post is part of our Week in Review series. Check back each week for a quick round up of interesting news and announcements from AWS!

Welcome to the March 14 AWS Week in Review post, and Happy Pi Day! I hope you managed to catch some of our livestreamed Pi day celebration of the 16th birthday of Amazon Simple Storage Service (Amazon S3). I certainly had a lot of fun in the event, along with my co-hosts – check out the end of this post for some interesting facts and fun from the day.

First, let’s dive right into the news items and launches from the last week that caught my attention.

Last Week’s Launches
New X2idn and X2iedn EC2 Instance Types – Customers with memory-intensive workloads and a requirement for high networking bandwidth may be interested in the newly announced X2idn and X2iedn instance types, which are built on the AWS Nitro system. Featuring third-generation Intel Xeon Scalable (Ice Lake) processors, these instance types can yield up to 50 percent higher compute price performance and up to 45 percent higher SAP Application Performance Standard (SAPS) performance than comparable X1 instances. If you’re curious about the suffixes on those instance type names, they specify processor and other information. In this case, the i suffix indicates that the instances are using an Intel processor, e means it’s a memory-optimized instance family, d indicates local NVMe-based SSDs physically connected to the host server, and n means the instance types support higher network bandwidth up to 100 Gbps. You can find out more about the new instance types in this news blog post.

Amazon DynamoDB released two updates – First, an increase in the default service quotas raises the number of tables allowed by default from 256 to 2500 tables. This will help customers working with large numbers of tables. At the same time the service also increased the allowed number of concurrent table management operations, from 50 to 500. Table management operations are those that create, update, or delete tables. The second update relates to PartiQL a SQL-compatible query language you can use to query, insert, update, or delete DynamoDB table data. You can now specify a limit on the number of items processed. You’ll find this useful when you know you only need to process a certain number of items, helping reduce the cost and duration of requests.

If you’re coding against Amazon ECS‘s API, you may want to take a look at the change to UpdateService that now enables you to update load balancers, service registries, tag propagation, and ECS managed tags for a service. Previously, you would have had to delete and recreate the service to make changes to these resources for a service. Now you can do it all with one call, making it a hassle-free and less disruptive, more efficient experience. Take a look at the What’s New post for more details.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
If you’re analyzing time series data, take a look at this new book on building forecasting models and detecting anomalies in your data. It’s authored by Michael Hoarau, an AI/ML Specialist Solutions Architect at AWS.

March 8 was International Women’s Day and we published a post featuring several women, including fellow news blogger and published author Antje Barth, chatting about their experiences working in Developer Relations at AWS.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

.NET Application Modernization Webinar (March 23) – Sign up today to learn about .NET modernization, what it is, and why you might want to modernize. The webinar will include a deep dive focusing on the AWS Microservice Extractor for .NET.

AWS Summit Brussels is fast approaching on March 31st. Register here.

Pi Day Fun & Facts
As this post is published, we’re coming to the end of our livestreamed Pi Day event celebrating the 16th birthday of S3 – how time flies! Here are some interesting facts & fun snippets from the event:

  • In the keynote, we learned S3 currently stores over 200 trillion objects, and serves over 100 million requests per second!
  • S3‘s Intelligent Tiering has saved customers over $250 million to date.
  • Did you know that S3, having reached 16 years of age, is now eligible for a Washington State drivers license? Or that it can now buy a lottery ticket, get a passport, or – check this – it can pilot a hang glider!
  • We asked each of our guests on the livestream, and the team of AWS news bloggers, to nominate their favorite pie. The winner? It’s a tie between apple and pecan pie!

That’s all for this week. Check back next Monday for another Week in Review!

— Steve

Improving the reliability of file system monitoring tools (Collabora blog)

Post Syndicated from original https://lwn.net/Articles/887841/

Gabriel Krisman Bertazi describes
the new FAN_FS_ERROR event type
added to the fanotify
mechanism in 5.16.

This is why we worked on a new mechanism for closely monitoring
volumes and notifying recovery tools and sysadmins in real-time
that an error occurred. The feature, merged in kernel 5.16, won’t
prevent failures from happening, but will help reduce the effects
of such errors by guaranteeing any listener application receives
the message. A monitoring application can then reliably report it
to system administrators and forward the detailed error information
to whomever is unlucky enough to be tasked with fixing it.

Welcome to AWS Pi Day 2022

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/welcome-to-aws-pi-day-2022/

We launched Amazon Simple Storage Service (Amazon S3) sixteen years ago today!

As I often told my audiences in the early days, I wanted them to think big thoughts and dream big dreams! Looking back, I think it is safe to say that the launch of S3 empowered them to do just that, and initiated a wave of innovation that continues to this day.

Bigger, Busier, and more Cost-Effective
Our customers count on Amazon S3 to provide them with reliable and highly durable object storage that scales to meet their needs, while growing more and more cost-effective over time. We’ve met those needs and many others; here are some new metrics that prove my point:

Object Storage – Amazon S3 now holds more than 200 trillion (2 x 10¹⁴) objects. That’s almost 29,000 objects for each resident of planet Earth. Counting at one object per second, it would take 6.342 million years to reach this number! According to Ethan Siegel, there are about 2 trillion galaxies in the visible Universe, so that’s 100 objects per galaxy! Shortly after the 2006 launch of S3, I was happy to announce the then-impressive metric of 800 million stored objects, so the object count has grown by a factor of 250,000 in less than 16 years.

Request Rate – Amazon S3 now averages over 100 million requests per second.

Cost Effective – Over time we have added multiple storage classes to S3 in order to optimize cost and performance for many different workloads. For example, AWS customers are making great use of Amazon S3 Intelligent Tiering (the only cloud storage class that delivers automatic storage cost savings when data access patterns change), and have saved more than $250 million in storage costs as compared to Amazon S3 Standard. When I first wrote about this storage class in 2018, I said:

In order to make it easier for you to take advantage of S3 without having to develop a deep understanding of your access patterns, we are launching a new storage class, S3 Intelligent-Tiering.

With the improved cost optimizations for small and short-lived objects and the archiving capabilities that we launched late last year, you can now use S3 Intelligent-Tiering as the default storage class for just about every workload, especially data lakes, analytics use cases, and new applications.

Customer Innovation
As you can see from the metrics above, our customers use S3 to store and protect vast amounts of data in support of an equally vast number of use cases and applications. Here are just a few of the ways that our customers are innovating:

NASCAR – After spending 15 years collecting video, image, and audio assets representing over 70 years of motor sports history, NASCAR built a media library that encompassed over 8,600 LTO 6 tapes and a few thousand LTO 4 tapes, with a growth rate of between 1.5 PB and 2 PB per year. Over the course of 18 months they migrated all of this content (a total of 15 PB) to AWS, making use of the Amazon S3 Standard, Amazon S3 Glacier Flexible Retrieval, and Amazon S3 Glacier Deep Archive storage classes. To learn more about how they migrated this massive and invaluable archive, read Modernizing NASCAR’s multi-PB media archive at speed with AWS Storage.

Electronic Arts –
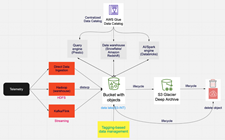
This game maker’s core telemetry systems handle tens of petabytes of data, tens of thousands of tables, and over 2 billion objects. As their games became more popular and the volume of data grew, they were facing challenges around data growth, cost management, retention, and data usage. In a series of updates, they moved archival data to Amazon S3 Glacier Deep Archive, implemented tag-driven retention management, and implemented Amazon S3 Intelligent-Tiering. They have reduced their costs and made their data assets more accessible; read
Electronic Arts optimizes storage costs and operations using Amazon S3 Intelligent-Tiering and S3 Glacier to learn more.

NRGene / CRISPR-IL –
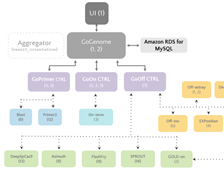
This team came together to build a best-in-class gene-editing prediction platform. CRISPR (
A Crack In Creation is a great introduction) is a very new and very precise way to edit genes and effect changes to an organism’s genetic makeup. The CRISPR-IL consortium is built around an iterative learning process that allows researchers to send results to a predictive engine that helps to shape the next round of experiments. As described in
A gene-editing prediction engine with iterative learning cycles built on AWS, the team identified five key challenges and then used AWS to build GoGenome, a web service that performs predictions and delivers the results to users. GoGenome stores over 20 terabytes of raw sequencing data, and hundreds of millions of feature vectors, making use of Amazon S3 and other
AWS storage services as the foundation of their data lake.

Some other cool recent S3 success stories include Liberty Mutual (How Liberty Mutual built a highly scalable and cost-effective document management solution), Discovery (Discovery Accelerates Innovation, Cuts Linear Playout Infrastructure Costs by 61% on AWS), and Pinterest (How Pinterest worked with AWS to create a new way to manage data access).

Join Us Online Today
In celebration of AWS Pi Day 2022 we have put together an entire day of educational sessions, live demos, and even a launch or two. We will also take a look at some of the newest S3 launches including Amazon S3 Glacier Instant Retrieval, Amazon S3 Batch Replication and AWS Backup Support for Amazon S3.

Designed for system administrators, engineers, developers, and architects, our sessions will bring you the latest and greatest information on security, backup, archiving, certification, and more. Join us at 9:30 AM PT on Twitch for Kevin Miller’s kickoff keynote, and stick around for the entire day to learn a lot more about how you can put Amazon S3 to use in your applications. See you there!

— Jeff;

[$] Triggering huge-page collapse from user space

Post Syndicated from original https://lwn.net/Articles/887753/

When the kernel first gained support for
huge pages, most of the work was left to user space. System administrators
had to set
aside memory in the special hugetlbfs filesystem
for huge pages, and
programs had to explicitly map memory from there. Over time, the transparent huge pages mechanism automated the
task of using huge pages. That mechanism is not perfect, though, and some
users feel that they have better knowledge of when huge-page use makes sense
for a given process. Thus, huge pages are now coming full circle with this patch
set
from Zach O’Keefe returning huge pages to user-space control.

Upcoming Speaking Events

Post Syndicated from Schneier.com Webmaster original https://www.schneier.com/blog/archives/2022/03/upcoming-speaking-events.html

This is a current list of where and when I am scheduled to speak:

  • I’m participating in an online panel discussion on “Ukraine and Russia: The Online War,” hosted by UMass Amherst, at 5:00 PM Eastern on March 31, 2022.
  • I’m speaking at Future Summits in Antwerp, Belgium on May 18, 2022.
  • I’m speaking at IT-S Now 2022 in Vienna on June 2, 2022.
  • I’m speaking at the 14th International Conference on Cyber Conflict, CyCon 2022, in Tallinn, Estonia on June 3, 2022.
  • I’m speaking at the RSA Conference 2022 in San Francisco, June 6-9, 2022.
  • I’m speaking at the Dublin Tech Summit in Dublin, Ireland, June 15-16, 2022.

The list is maintained on this page.

Security updates for Monday

Post Syndicated from original https://lwn.net/Articles/887807/

Security updates have been issued by Debian (expat, haproxy, libphp-adodb, nbd, and vim), Fedora (chromium, cobbler, firefox, gnutls, linux-firmware, radare2, thunderbird, and usbguard), Mageia (gnutls), Oracle (.NET 5.0, .NET 6.0, .NET Core 3.1, firefox, and kernel), SUSE (firefox, tomcat, and webkit2gtk3), and Ubuntu (libxml2 and nbd).

An Inside Look at CISA’s Supply Chain Task Force

Post Syndicated from Chad Kliewer, MS, CISSP, CCSP original https://blog.rapid7.com/2022/03/14/an-inside-look-at-cisas-supply-chain-task-force/

An Inside Look at CISA’s Supply Chain Task Force

When one mentions supply chains these days, we tend to think of microchips from China causing delays in automobile manufacturing or toilet paper disappearing from store shelves. Sure, there are some chips in the communications infrastructure, but the cyber supply chain is mostly about virtual things – the ones you can’t actually touch.  

In 2018, the Cybersecurity and Infrastructure Security Agency (CISA) established the Information and Communications Technology (ICT) Supply Chain Risk Management (SCRM) Task Force as a public-private joint effort to build partnerships and enhance ICT supply chain resilience. To date, the Task Force has worked on 7 Executive Orders from the White House that underscore the importance of supply chain resilience in critical infrastructure.

Background

The ICT-SCRM Task Force is made up of members from the following sectors:

  • Information Technology (IT) – Over 40 IT companies, including service providers, hardware, software, and cloud have provided input.
  • Communications – Nearly 25 communications associations and companies are included, with representation from the wireline, wireless, broadband, and broadcast areas.
  • Government – More than 30 government organizations and agencies are represented on the Task Force.

These three sector groups touch nearly every facet of critical infrastructure that businesses and government require. The Task Force is dedicated to identifying threats and developing solutions to enhance resilience by reducing the attack surface of critical infrastructure. This diverse group is poised perfectly to evaluate existing practices and elevate them to new heights by enhancing existing standards and frameworks with up-to-date practical advice.

Working groups

The core of the task force is the working groups. These groups are created and disbanded as needed to address core areas of the cyber supply chain. Some of the working groups have been concentrating on areas like:

  • The legal risks of information sharing
  • Evaluating supply chain threats
  • Identifying criteria for building Qualified Bidder Lists and Qualified Manufacturer Lists
  • The impacts of the COVID-19 pandemic on supply chains
  • Creating a vendor supply chain risk management template

Ongoing efforts

After two years of producing some great resources and rather large reports, the ICT-SCRM Task Force recognized the need to ensure organizations of all sizes can take advantage of the group’s resources, even if they don’t have a dedicated risk management professional at their disposal. This led to the creation of both a Small and Medium Business (SMB) working group, as well as one dedicated to Product Marketing.

The SMB working group chose to review and adapt the Vendor SCRM template for use by small and medium businesses, which shows the template can be a great resource for companies and organizations of all sizes.  

Out of this template, the group described three cyber supply chain scenarios that an SMB (or any size organization, really) could encounter. From that, the group further simplified the process by creating an Excel spreadsheet that provides a document that is easy for SMBs to share with their prospective vendors and partners as a tool to evaluate their cybersecurity posture. Most importantly, the document does not promote a checkbox approach to cybersecurity — it allows for partial compliance, with room provided for explanations. It also allows many of the questions to be removed if the prospective partner possesses a SOC1/2 certification, thereby eliminating duplication in questions.

What the future holds

At the time of this writing, the Product Marketing and SMB working groups are hard at work making sure everyone, including the smallest businesses, are using the ICT-SCRM Task Force Resources to their fullest potential. Additional workstreams are being developed and will be announced soon, and these will likely include expansion with international partners and additional critical-infrastructure sectors.

For more information, you can visit the CISA ICT-SCRM Task Force website.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Extend SQL Server DR using log shipping for SQL Server FCI with Amazon FSx for Windows configuration

Post Syndicated from Yogi Barot original https://aws.amazon.com/blogs/architecture/extend-sql-server-dr-using-log-shipping-for-sql-server-fci-with-amazon-fsx-for-windows-configuration/

This week for Women’s History Month, we’re continuing to feature female authors. We’re showcasing women in the tech industry who are building, creating, and, above all, inspiring, empowering, and encouraging everyone—especially women and girls—in tech.


Companies choosing to rehost their on-premises SQL Server workloads to AWS can face challenges with setting up their disaster recovery (DR) strategy. Solutions such as Always On can be a more expensive, complex configuration across Regions. It can cause latency issues when synchronously replicating data cross-Region. Snapshots have additional overhead and may breach their stringent recovery point objective/recovery time objective (RPO/RTO) requirements.

A log shipping solution can take advantage of cross-Region replication of data using Amazon FSx for Windows File Server. It has less maintenance overhead, doesn’t introduce latency, and meets RPO/RTO requirements. A multi-Region architecture for Microsoft SQL Server is often adopted for SQL Server deployments for business continuity (disaster recovery) and improved latency (for a geographically distributed customer base).

This blog post explores SQL Server DR architecture using SQL Server failover cluster with Amazon FSx for Windows File Server for the primary site and secondary DR site. We describe how to set up a multi-Region DR using log shipping. We’ll explain the architecture patterns so you can follow along and effectively design a highly available SQL Server deployment that spans two or more AWS Regions.

Here are some advantages of using log shipping versus Always On distributed availability group DR setup.

  • Log shipping works with SQL Server Standard edition
  • It lowers total cost of ownership (TCO) as you only need one SQL Server Standard edition license at the primary/DR site
  • It’s straightforward to configure
  • There’s no need for clustering setup at the OS level
  • It supports all SQL Server versions. You don’t need the SQL Server version to be the same for source and destination instances.

Log shipping DR solution for SQL Server FCI with Amazon FSx

The architecture diagram in Figure 1 depicts SQL Server failover cluster instance (FCI) using Amazon FSx as storage (multiple Availability Zones) in Region 1. It uses a standalone or a similar setup on Region 2. It uses a log shipping feature for replication and DR. This will also serve as the reference architecture for our solution.

Log shipping DR solution for SQL Server FCI with Amazon FSx

Figure 1. Log shipping DR solution for SQL Server FCI with Amazon FSx

Figure 1 shows an SQL cluster in Region 1 and standalone SQL cluster in Region 2. The primary cluster in Region 1 is initially configured with SQL Server failover cluster instance (FCI) using Amazon FSx for its shared storage. Region 2 can have a standalone Amazon EC2 server with SQL Server and Amazon Elastic Block Store (EBS) as storage. Or it can have an identical configuration to Region 1, but with different hostnames, and an SQL network name (SQLFCI02) to avoid possible collisions.

You can build the VPC peering or AWS Transit Gateway to have seamless connectivity between the two Regions for the opened ports (SQL Server, SMB for file share, and others.)

With Amazon FSx, you get a fully managed and shared file storage solution, that automatically replicates the underlying storage synchronously across multiple Availability Zones. Amazon FSx provides high availability with automatic failure detection and automatic failover if there are any hardware or storage issues. The service fully supports continuously available shares, a feature that permits SQL Server uninterrupted access to shared file data.

There is an asynchronous replication setup from Region 1 to Region 2 using the log shipping feature. In this type of configuration, Microsoft SQL Server log shipping replicates databases using transaction logs. This ensures that a physically replicated warm standby database is an exact binary replica of the primary database. This is referred to as physical replication.

Log shipping can be configured with two available modes. These are related to the state of the secondary log-shipped SQL Server database.

  • Standby mode. The database is available for querying. Users cannot access the database while restore is going on. But once restore is completed, users can access it in read-only mode.
  • Restore mode. The database is not accessible for users.

In this solution, you configure a warm standby SQL Server database on an EC2 instance designated in SQL FCI using Amazon FSx as shared storage. You can send transaction log backups asynchronously between your primary Region database and the warm standby server in the other Region. The transaction log backups are then applied to the warm standby database sequentially. When all the logs have been applied, you can perform a manual failover and point the application to the secondary Region. We recommend running the primary and secondary database instances in separate Availability Zones, and configuring a monitor instance to track all the details of log shipping.

Prerequisites

Walkthrough steps to set up DR for SQL Server FCI

Following are the steps required to configure SQL Server DR using SQL Server failover cluster. Amazon FSx for Windows File Server is used for the primary site and secondary DR site. We also demonstrate how to set up a multi-Region log shipping.

Assumed variables

Region_01:
WSFC Cluster Name: SQLCluster1
FCI Virtual Network Name: SQLFCI01
Region_02:
Amazon EC2 Name: EC2SQL2

Make sure to configure network connectivity between your clusters. In this solution, we are using two VPCs in two separate Regions.

    • VPC peering is configured to enable network traffic on both VPCs.
    • The domain controller (AWS Managed Microsoft AD) on both VPCs are configured with conditional forwarding. This enables DNS resolution between the two VPCs.
  1. Configure SQL FCI setup using Amazon FSx as shared storage on Region_01.
  2. Configure SQL standalone instance on Region_02 with EBS volume as storage.
  3. Create an Amazon FSx in the primary Region with AWS managed Active Directory, or on-premises Active Directory connected with trust relation or AD Connector.
  4. Create a SQL Server service account with proper permissions to be able to set up transaction log settings.
  5. Configure VPC peering between the primary and DR/secondary Region.
  6. Join the domain to the Active Directory network for both primary and secondary servers in primary Region.
  7. Mount Amazon FSx on primary and secondary server and allow shared permissions, so SQL Server is able to access the folder. Use Amazon FSx for storing transaction log backups and EBS for storing transaction logs on the secondary Region.
  8. Set up log shipping from the primary server SQL Server FCI01 to the secondary SQL Server EC2SQL2 with the standby option enabled. This way the databases can be in read on the secondary SQL Server.
  9. In case of disaster, follow the FAILOVER and FAILBACK steps in the next sections. Learn more by reading Change Roles Between Primary and Secondary Log Shipping Servers.

Failover steps

In case of disaster at primary Region node SQLFCI01, log shipping acts as DR solution. Following, we show the steps to bring the databases online on EC2SQL02. Once SQLFCI01 is back, Use the following steps if DR drill checks to failover. In a real disaster, follow the process from Step 3 onwards.

1. Stop all activities on SQLFCI01 databases involved in log shipping jobs on SQLFCI01 and EC2SQL02. Confirm if any process is running by using the following query:

Use master
Go
select * from sysprocesses where dbid = DB_ID('DatabaseName')

2. Take full backup on SQLFCI01 as rollback option.

BACKUP DATABASE [DatabaseName]
TO  DISK = N'Provide Drive details'
WITH COMPRESSION
GO

3. Take last tail transaction log backup if we have access to SQL Server. Otherwise, check the last available transaction log stored in EC2SQL02 and restore it with RECOVERY to bring the databases online on EC2SQL02.

RESTORE LOG [DatabaseName] FROM  DISK = N'Provide path of last tlog'
WITH  FILE = 1,  RECOVERY,  NOUNLOAD,  STATS = 10
GO

4. Redirect the application connections to EC2SQL02.

Failback methods

1. Native backup/restore or rollback strategy

  • Take full backup from EC2SQL02 and copy to the SQLFCI01.
  • RESTORE the full backup on SQLFCI01.
  • Reconfigure log shipping between SQLFCI01 and EC2SQL02.

2.    Reverse log shipping

In case of DR drills or business continuity and disaster recovery (BCDR) activities, we can set up reverse log shipping to reduce the time taken to failover. It doesn’t require reinitializing the database with a full backup if performed carefully. It is crucial to preserve the log sequence number (LSN) chain. Perform the final log backup using the NORECOVERY option. Backing up the log with this option puts the database in a state where log backups can be restored. It ensures that the database’s LSN chain doesn’t deviate. This procedure helps reduce downtime to bring back SQLFCI01.

  • STOP all activities on SQLFCI01 databases involved in log shipping jobs on SQLFCI01 and EC2SQL02.
  • TAKE Tlog backup of SQLFCI01 with NORECOVERY option.

BACKUP LOG [DatabaseName]
TO DISK = 'BackupFilePathname'
WITH NORECOVERY;

  • RESTORE transaction log backup on EC2SQL02 with NORECOVERY.
  • Reconfigure log shipping and reenable the jobs back.
  • Reconfigure the application connections to SQLFCI01.

Conclusion

A multi-Region strategy for your mission-critical SQL Server deployments is key for business continuity and disaster recovery. This blog post shows how to achieve that using log shipping for SQL Server FCI deployment. Setting up DR using log shipping can help you save costs and meet your business requirements.

To learn more, check out Simplify your Microsoft SQL Server high availability deployments using Amazon FSx for Windows File Server.

More posts for Women’s History Month!

Other ways to participate

Democratizing email security: protecting individuals and businesses of all sizes from phishing and malware attacks

Post Syndicated from Patrick R. Donahue original https://blog.cloudflare.com/democratizing-email-security/

Democratizing email security: protecting individuals and businesses of all sizes from phishing and malware attacks

Democratizing email security: protecting individuals and businesses of all sizes from phishing and malware attacks

Since our founding, Cloudflare has been on a mission to take expensive, complex security solutions typically only available to the largest companies and make them easy to use and accessible to everyone. In 2011 and 2015 we did this for the web application firewall and SSL/TLS markets, simplifying the process of protecting websites from application vulnerabilities and encrypting HTTP requests down to single clicks; in 2020, during the start of the COVID-19 pandemic, we made our Zero Trust suite available to everyone; and today—in the face of heightened phishing attacks—we’re doing the same for the email security market.

Once the acquisition of Area 1 closes, as we expect early in the second quarter of 2022, we plan to give all paid self-serve plans access to their email security technology at no additional charge. Control, customization, and visibility via analytics will vary with plan level, and the highest flexibility and support levels will be available to Enterprise customers for purchase.

All self-serve users will also get access to a more feature-packed version of the Zero Trust solution we made available to everyone in 2020. Zero Trust services are incomplete without an email security solution, and CISA’s recent report makes that clearer than ever: over 90% of successful cyber attacks start with a phishing email, so we expect that over time analysts will have no choice but to include email in their definitions of secure access and zero edges.

If you’re interested in reserving your place in line, register your interest by logging into your Cloudflare account at dash.cloudflare.com, selecting your domain, clicking Email, and then “Join Waitlist” at the top of the page; we’ll reach out after the Area 1 acquisition is completed, and the integration is ready, in the order we received your request.

One-click deployment

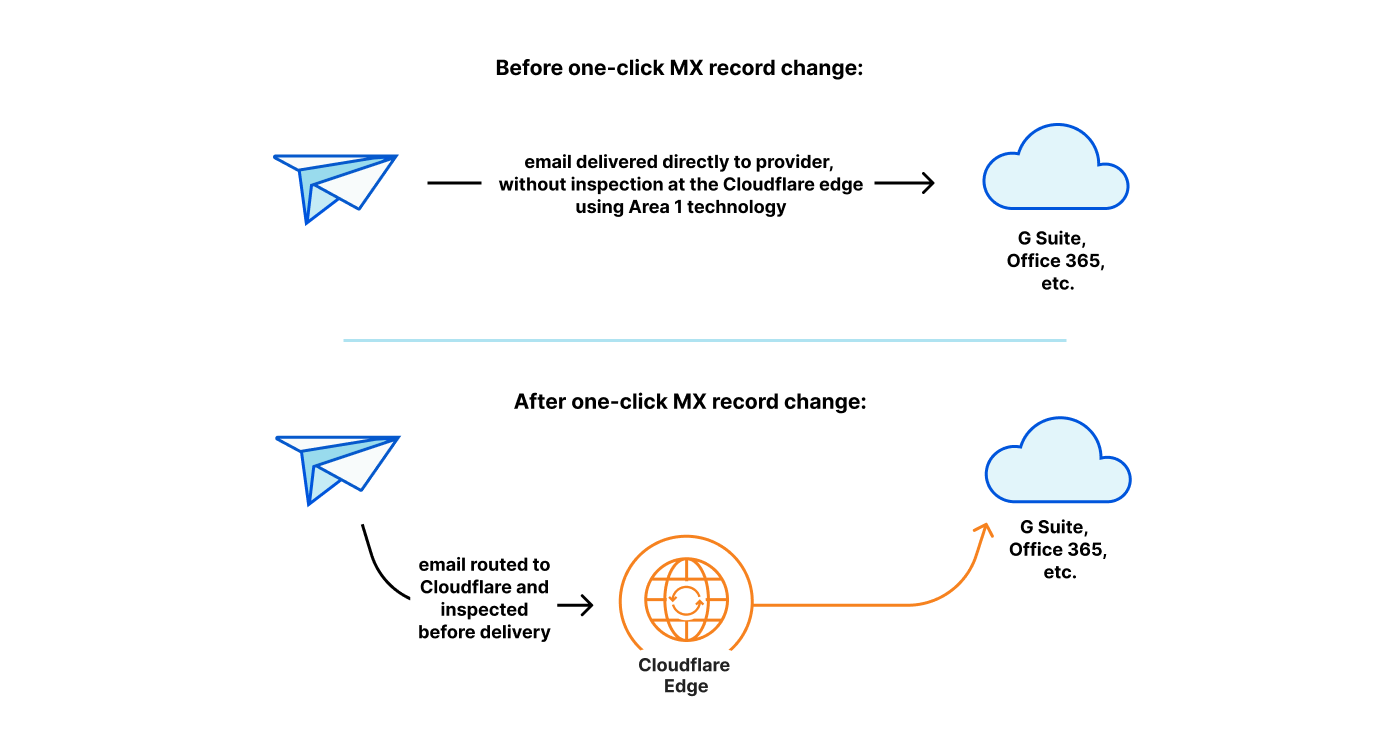
If you’re already managing your authoritative DNS with Cloudflare, as nearly 100% of non-Enterprise plans are, there will just be a single click to get started. Once clicked, we’ll start returning different MX records to anyone trying to send email to your domain. This change will attract all emails destined for your domain, during which they’ll be run through Area 1’s models and potentially be quarantined or flagged. Customers of Microsoft Office 365 will also be able to take advantage of APIs for an even deeper integration and capabilities like post-delivery message redaction.

Democratizing email security: protecting individuals and businesses of all sizes from phishing and malware attacks

In addition to routing and filtering email, we’ll also automagically take care of your DNS email security records such as SPF, DKIM, DMARC, etc. We launched a tool to help with this last year, and soon we’ll be making it even more comprehensive and easier to use.

Integration with other Zero Trust products

As we wrote in the acquisition announcement post on this blog, we’re excited to integrate email security with other products in our Zero Trust suite. For customers of Gateway and Remote Browser Isolation (RBI), we’ll automatically route potentially suspicious domains and links through these protective layers. Our built-in data loss prevention (DLP) technology will also be wired into Area 1’s technology in deployments where visibility into outbound email is available.

Improving threat intelligence with new data sources

In addition to integrating directly with Zero Trust products, we’re excited about connecting threat data sources from Area 1 into existing Cloudflare products and vice versa. For example, phishing infrastructure identified during Area 1’s Internet-wide scans will be displayed within the recently launched Cloudflare Security Center, and 1.1.1.1’s trillions of queries per month will help Area 1 identify new domains that may be threats. Domains that are newly registered, or registered with slight variations of legitimate domains, are often warning signs of an upcoming phishing attack.

Getting started

Cloudflare has been a happy customer of Area 1’s technology for years, and we’re excited to open it up to all of our customers as soon as possible. If you’re excited as we are about being able to use this in your Pro or Business plan, reserve your place in line today within the Email tab for your domain. Or if you’re an Enterprise customer and want to get started immediately, fill out this form or contact your Customer Success Manager.

Investigating threats using the Cloudflare Security Center

Post Syndicated from Patrick R. Donahue original https://blog.cloudflare.com/security-center-investigate/

Investigating threats using the Cloudflare Security Center

Investigating threats using the Cloudflare Security Center

Cloudflare blocks a lot of diverse security threats, with some of the more interesting attacks targeting the “long tail” of the millions of Internet properties we protect. The data we glean from these attacks trains our machine learning models and improves the efficacy of our network and application security products, but historically hasn’t been available to query directly. This week, we’re changing that.

All customers will soon be granted access to our new threat investigations portal, Investigate, in the Cloudflare Security Center (first launched in December 2021). Additionally, we’ll be annotating threats across our analytics platform with this intelligence to streamline security workflows and tighten feedback loops.

What sorts of data might you want to look up here? Let’s say you’re seeing an IP address in your logs and want to learn which hostnames have pointed to it via DNS, or you’re seeing a cluster of attacks come from an autonomous system (AS) you’re not familiar with. Or maybe you want to investigate a domain name to see how it’s been categorized from a threat perspective. Simply enter any of those items into the omni search box, and we’ll tell you everything we know.

IPs and hostnames will be available to query this week, followed by AS details to give you insight into the networks that communicate with your Cloudflare accounts. Next month as we move to general availability we’ll add data types and properties. Integrations with partners will allow you to use your existing license keys to see all your threat data in a single, unified interface. We also plan to show how both your infrastructure and corporate employees are interacting with any objects you look up, e.g., you can see how many times an IP triggers a WAF or API Shield rule, or how many times your employees attempted to resolve a domain that’s known to serve malware.

Annotations in the dashboard: actionable intelligence in context

Looking up threat data on an ad hoc basis is great, but it’s better when that data is annotated directly in logs and analytics. Starting this week, we will begin rolling out intelligence that is available in Investigate in the dashboard where it is relevant to your workflow. We’re starting with the web application firewall analytics for your websites that are behind Cloudflare.

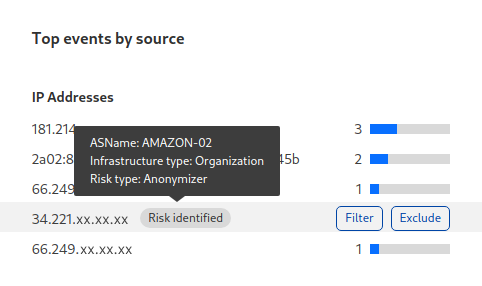
Say you are investigating a security alert for a large number of requests that are blocked by a web application firewall rule. You might see that the alert was caused by an IP address probing your website for commonly exploited software vulnerabilities. If the IP in question were a cloud IP or flagged as an anonymizer, contextual intelligence will show that information directly on the analytics page.

This context can help you see patterns. Are attacks coming from anonymizers or the Tor network? Are they coming from cloud virtual machines? An IP is just an IP. But seeing a credential stuffing attack coming from anonymizers is a pattern that enables a proactive response, “Is my bot management configuration up-to-date?”

Investigating threats using the Cloudflare Security Center

Cloudflare’s network vantage point and how this informs our data

The scale at which each product suite operates at Cloudflare is staggering. At peak, Cloudflare handles 44 million HTTP requests a second, from more than 250 cities in over 100 countries. The Cloudflare network responds to over 1.2 trillion DNS queries per day, and it has 121 Tbps of network capacity to serve traffic and mitigate denial of service attacks across all products. But on top of this immense scale, Cloudflare’s architecture enables refining raw data and combining intelligence from all of our products to paint a holistic picture of the security landscape.

We are able to take signals refined from the raw data generated by each product and combine them with signals from other products and capabilities to enhance our network and threat data capabilities. It is a common paradigm for security products to be built to have positive flywheel effects among users of the products. If one customer sees a new piece of malware, an endpoint protection vendor can deploy an update that will detect and block this malware for all their other customers. If a botnet attacks one customer, this provides information that can be used to find the signature of that botnet and protect other customers. If a device participates in a DDoS (Distributed Denial of Service) attack, that information can be used to make the network able to faster detect and mitigate future DDoS attacks. Cloudflare’s breadth of product offerings means that the flywheel effect benefits to users accumulate not just between users, but between products as well.

Let’s look at some examples:

DNS resolution and certificate transparency

First, Cloudflare operates 1.1.1.1, one of the largest recursive DNS resolvers in the world. We operate it in a privacy-forward manner, so here at Cloudflare we do not know who or what IP performed a query, nor are we able to correlate queries together to distinct anonymous users. However, through the requests the resolver handles, Cloudflare sees newly registered and newly seen domains. Additionally, Cloudflare has one of the most advanced SSL/TLS encryption products on the market, and as part of that is a member organization helping to maintain the Certificate Transparency logs. These are public logs of every TLS certificate issued by a root certificate authority that is trusted by web browsers. Between these two products, Cloudflare has an unmatched view of what domains are out there on the Internet and when they become active. We use this information not only to populate our new and newly seen domains categories for our Gateway product, but we feed these domains into machine learning models that label suspicious or potentially malicious domains early in their lifecycle.

Email security

As another example, with the acquisition of Area 1, Cloudflare will bring a new set of mutually-reinforcing capabilities into its product offering. All the signals we can generate for a domain from our 1.1.1.1 resolver will become available to help identify malicious email, and Area 1’s years of expertise in identifying malicious email will be able to feed back into Cloudflare’s Gateway product and 1.1.1.1 for Families DNS resolver. In the past, data integrations like this would have been performed by IT or security teams. Instead, data will be able to flow seamlessly between the points on your organization’s attack surface, mutually reinforcing the quality of the analysis and classification. The entire Cloudflare Zero Trust toolkit, including request logging, blocking, and remote browser isolation will be available to handle potentially malicious links delivered via email, using the same policies already in place for other security risks.

Over the last few years, Cloudflare has integrated the use of machine learning in many of our product offerings, but today we’ve launched a new tool that puts the data and signals that power our network security into our customer’s hands as well. Whether responding to security incidents, threat hunting, or proactively setting security policies to protect for your organization, you, human, can now be part of the Cloudflare network as well. Cloudflare’s unique position in the network means that your insights can be fed back into the network to protect not just your organization across all Cloudflare products it uses, but also can participate in mutual insight and defense among all Cloudflare customers.

Looking forward

Cloudflare can cover your organization’s whole attack surface: defending websites, protecting devices and SaaS applications with Cloudflare Zero Trust, your locations and offices with Magic Transit, and your email communications. Security Center is here to make sure you have all the information you need to understand the cyber security risks present today, and to help you defend your organization using Cloudflare.

“What is the wiper malware that I hear about on the news, and how do I protect my company from it?” We hear your questions, and we’re going to give you answers. Not just raw information, but what is relevant to you and how you use the Internet. We have big plans for Security Center. A file scanning portal will provide you with information about JavaScript files seen by Page Shield, executable files scanned by Gateway, and the ability to upload and scan files. Indicators of Compromise like IP addresses and domains will link to information about the relevant threat actors, when known, giving you more information about the techniques and tactics you are faced with, and information about how Cloudflare products can be used to defend against them. CVE search will let you find information on software vulnerabilities, along with the same easy-to-understand Cloudflare perspective you are used to reading on this blog to help decode the jargon and technical language. With today’s release, we’re just getting started.

Get full observability into your Cloudflare logs with New Relic

Post Syndicated from Tanushree Sharma original https://blog.cloudflare.com/announcing-the-new-relic-direct-log-integration/

Get full observability into your Cloudflare logs with New Relic

Get full observability into your Cloudflare logs with New Relic

Building a great customer experience is at the heart of any business. Building resilient products is half the battle — teams also need observability into their applications and services that are running across their stack.

Cloudflare provides analytics and logs for our products in order to give our customers visibility to extract insights. Many of our customers use Cloudflare along with other applications and network services and want to be able to correlate data through all of their systems.

Understanding normal traffic patterns, causes of latency and errors can be used to improve performance and ultimately the customer experience. For example, for websites behind Cloudflare, analyzing application logs and origin server logs along with Cloudflare’s HTTP request logs give our customers an end-to-end visibility about the journey of a request.

We’re excited to have partnered with New Relic to create a direct integration that provides this visibility. The direct integration with our logging product, Logpush, means customers no longer need to pay for middleware to get their Cloudflare data into New Relic. The result is a faster log delivery and fewer costs for our mutual customers!

We’ve invited the New Relic team to dig into how New Relic One can be used to provide insights into Cloudflare.

New Relic Log Management

New Relic provides an open, extensible, cloud-based observability platform that gives visibility into your entire stack. Logs, metrics, events, and traces are automatically correlated to help our customers improve user experience, accelerate time to market, and reduce MTTR.

Deploying log management in context and at scale has never been faster, easier, or more attainable. With New Relic One, you can collect, search, and correlate logs and other telemetry data from applications, infrastructure, network devices, and more for faster troubleshooting and investigation.

New Relic correlates events from your applications, infrastructure, serverless environments, along with mobile errors, traces and spans to your logs — so you find exactly what you need with less toil. All your logs are only a click away, so there’s no need to dig through logs in a separate etool to manually correlate them with errors and traces.

See how engineers have used logs in New Relic to better serve their customers in the short video below.

A quickstart for Cloudflare Logpush and New Relic

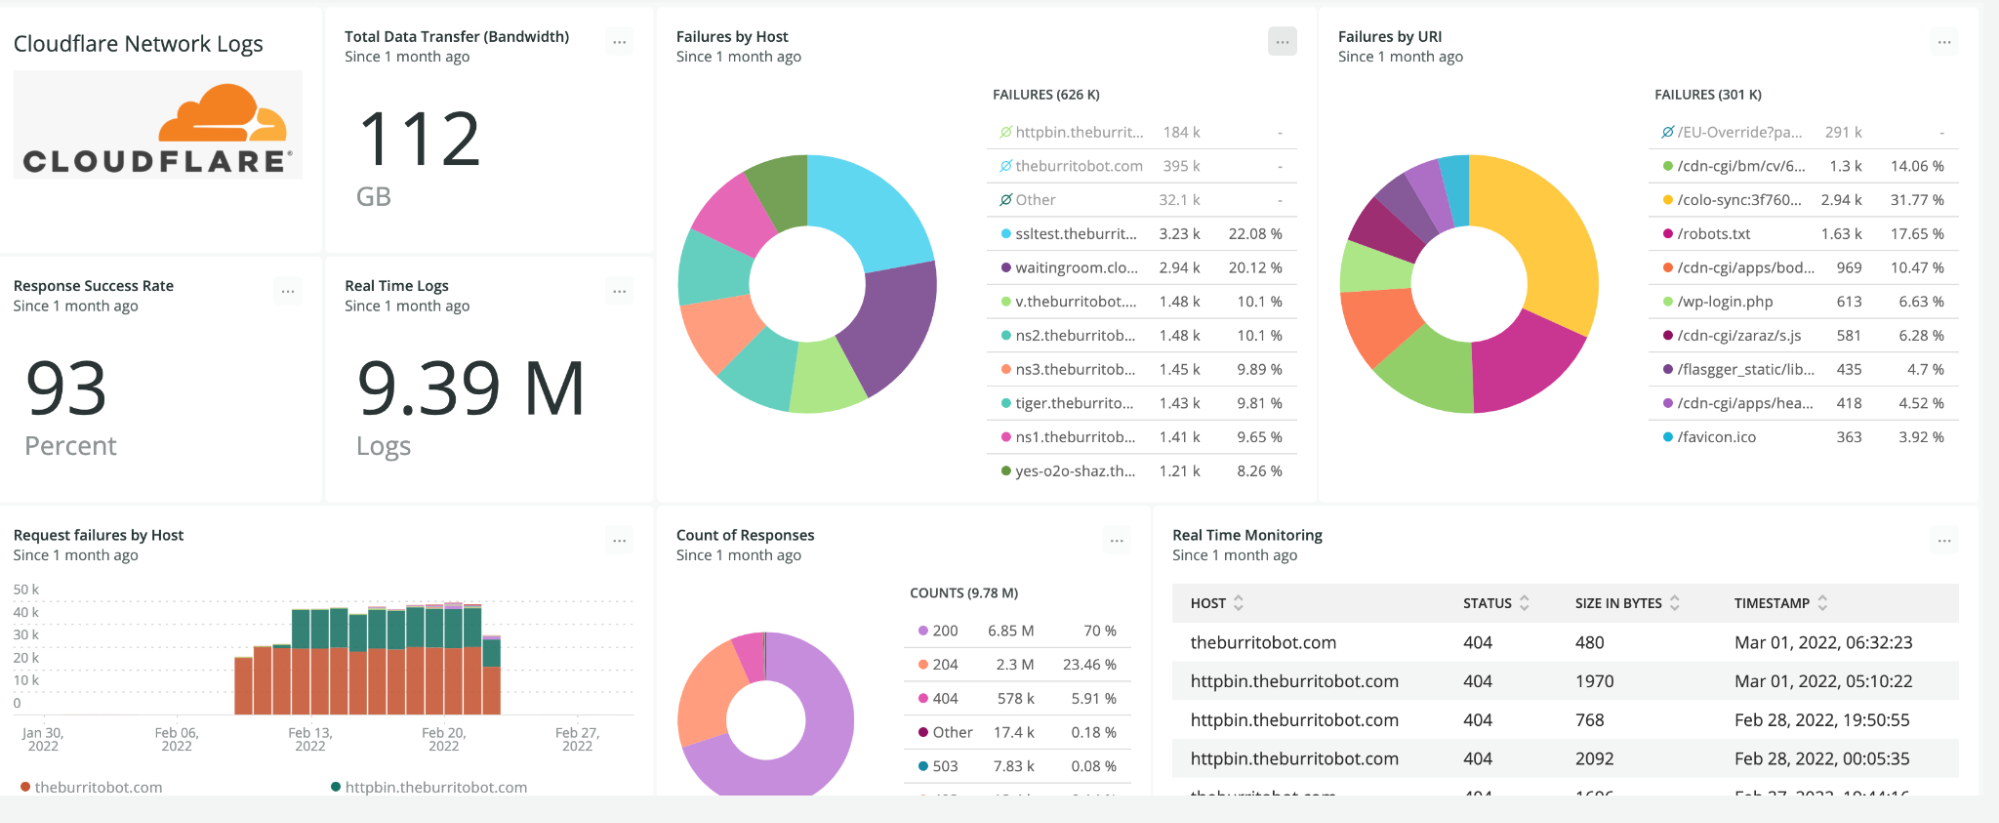
To help you get the most of the new Logpush integration with New Relic, we’ve created the Cloudflare Logpush quickstart for New Relic. The Cloudflare quickstart will enable you to monitor and analyze web traffic metrics on a single pre-built dashboard, integrating with New Relic’s database to provide an at-a-glance overview of the most important logs and metrics from your websites and applications.

Getting started is simple:

  • First, ensure that you have enabled pushing logs directly into New Relic by following the documentation “Enable Logpush to New Relic”.
  • You’ll also need a New Relic account. If you don’t have one yet, get a free-forever account here.
  • Next, visit the Cloudflare quickstart in New Relic, click “Install quickstart”, and follow the guided click-through.

For full instructions to set up the integration and quickstart, read the New Relic blog post.

Get full observability into your Cloudflare logs with New Relic

As a result, you’ll get a rich ready-made dashboard with key metrics about your Cloudflare logs!

Correlating Cloudflare logs across your stack in New Relic One is powerful for monitoring and debugging in order to keep services safe and reliable. Cloudflare customers get access to logs as part of the Enterprise account, if you aren’t using Cloudflare Enterprise, contact us. If you’re not already a New Relic user, sign up for New Relic to get a free account which includes this new experience and all of our product capabilities.

Leverage IBM QRadar SIEM to get insights from Cloudflare logs

Post Syndicated from Tanushree Sharma original https://blog.cloudflare.com/announcing-the-ibm-qradar-direct-log-integration/

Leverage IBM QRadar SIEM to get insights from Cloudflare logs

Leverage IBM QRadar SIEM to get insights from Cloudflare logs

It’s just gone midnight, and you’ve just been notified that there is a malicious IP hitting your servers. You need to triage the situation; find the who, what, where, when, why as fast and in as much detail as possible.

Based on what you find out, your next steps could fall anywhere between classifying the alert as a false positive, to escalating the situation and alerting on-call staff from around your organization with a middle of the night wake up.

For anyone that’s gone through a similar situation, you’re aware that the security tools you have on hand can make the situation infinitely easier. It’s invaluable to have one platform that provides complete visibility of all the endpoints, systems and operations that are running at your company.

Cloudflare protects customers’ applications through application services: DNS, CDN and WAF to name a few. We also have products that protect corporate applications, like our Zero Trust offerings Access and Gateway. Each of these products generates logs that provide customers visibility into what’s happening in their environments. Many of our customers use Cloudflare’s services along with other network or application services, such as endpoint management, containerized systems and their own servers.

We’re excited to announce that Cloudflare customers are now able to push their logs directly to IBM Security QRadar SIEM. This direct integration leads to cost savings and faster log delivery for Cloudflare and QRadar SIEM customers because there is no intermediary cloud storage required.

Cloudflare has invited our partner from the IBM QRadar SIEM team to speak to the capabilities this unlocks for our mutual customers.

IBM QRadar SIEM

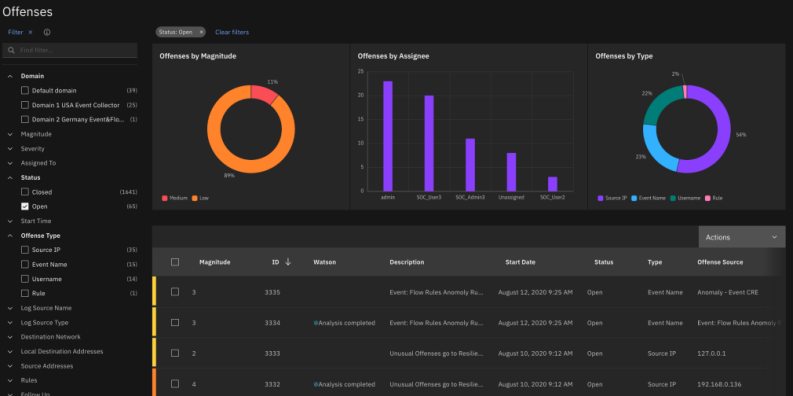
QRadar SIEM provides security teams centralized visibility and insights across users, endpoints, clouds, applications, and networks – helping you detect, investigate, and respond to threats enterprise wide. QRadar SIEM helps security teams work quickly and efficiently by turning thousands to millions of events into a manageable number of prioritized alerts and accelerating investigations with automated, AI-driven enrichment and root cause analysis. With QRadar SIEM, increase the productivity of your team, address critical use cases, and mature your security operation.

Cloudflare’s reverse proxy and enterprise security products are a key part of customer’s environments. Security analysis can gain visibility about logs from these products along with data from tools that span their network to build out detections and response workflows.

Leverage IBM QRadar SIEM to get insights from Cloudflare logs

IBM and Cloudflare have partnered together for years to provide a single pane of glass view for our customers. This new enhanced integration means that QRadar SIEM customers can ingest Cloudflare logs directly from Cloudflare’s Logpush product. QRadar SIEM also continues to support customers who are leveraging existing integration via S3 storage.

For more information about how to use this new integration, refer to the Cloudflare Logs DSM guide. Also, check out the blog post on the QRadar Community blog for more details!

Introducing: Backup Certificates

Post Syndicated from Dina Kozlov original https://blog.cloudflare.com/introducing-backup-certificates/

Introducing: Backup Certificates

At Cloudflare, we pride ourselves in giving every customer the ability to provision a TLS certificate for their Internet application — for free. Today, we are responsible for managing the certificate lifecycle for almost 45 million certificates from issuance to deployment to renewal. As we build out the most resilient, robust platform, we want it to be “future-proof” and resilient against events we can’t predict.

Events that cause us to re-issue certificates for our customers, like key compromises, vulnerabilities, and mass revocations require immediate action. Otherwise, customers can be left insecure or offline. When one of these events happens, we want to be ready to mitigate impact immediately. But how?

By having a backup certificate ready to deploy — wrapped with a different private key and issued from a different Certificate Authority than the primary certificate that we serve.

Introducing: Backup Certificates

Events that lead to certificate re-issuance

Cloudflare re-issues certificates every day — we call this a certificate renewal. Because certificates come with an expiration date, when Cloudflare sees that a certificate is expiring soon, we initiate a new certificate renewal order. This way, by the time the certificate expires, we already have an updated certificate deployed and ready to use for TLS termination.

Unfortunately, not all certificate renewals are initiated by the expiration date. Sometimes, unforeseeable events like key compromises can lead to certificate renewals. This is because a new key needs to be issued, and therefore a corresponding certificate does as well.

Key Compromises

A key compromise is when an unauthorized person or system obtains the private key that is used to encrypt and decrypt secret information — security personnel’s worst nightmare. Key compromises can be the result of a vulnerability, such as Heartbleed, where a bug in a system can cause the private key to be leaked. They can also be the result of malicious actions, such as a rogue employee accessing unauthorized information. In the event of a key compromise, it’s crucial that (1) new private keys are immediately issued, (2) new certificates are deployed, and (3) the old certificates are revoked.

The Heartbleed Vulnerability

In 2014, the Heartbleed vulnerability was exposed. It allowed attackers to extract the TLS certificate private key for any server that was running the affected version of OpenSSL, a popular encryption library. We patched the bug and then as a precaution, quickly reissued private keys and TLS certificates belonging to all of our customers, even though none of our keys were leaked. Cloudflare’s ability to act quickly protected our customers’ data from being exposed.

Heartbleed was a wake-up call. At the time, Cloudflare’s scale was a magnitude smaller. A similar vulnerability at today’s scale would take us weeks, not hours to re-issue all of our customers certificates.

Now, with backup certificates, we don’t need to worry about initiating a mass re-issuance in a small time frame. Instead, customers will already have a certificate that we’ll be able to instantly deploy. Not just that, but the backup certificate will also be wrapped with a different key than the primary certificate, preventing it from being impacted by a key compromise.

Key compromises are one of the main reasons certificates need to be re-issued at scale. But other events can prompt re-issuance as well, including mass revocations by Certificate Authorities.

Mass Revocations from CAs

Today, the Certificate Authority/Browser Forum (CA/B Forum) is the governing body that sets the rules and standards for certificates. One of the Baseline Requirements set by the CA/B Forum states that Certificate Authorities are required to revoke certificates whose keys are at risk of being compromised within 24 hours. For less immediate issues, such as certificate misuse or violation of a CA’s Certificate Policy, certificates need to be revoked within five days. In both scenarios, certificates will be revoked by the CA in a short timeframe and immediate re-issuance of certificates is required.

While mass revocations aren’t commonly initiated by CAs, there have been a few occurrences throughout the last few years. Recently, Let’s Encrypt had to revoke roughly 2.7 million certificates when they found a non-compliance in their implementation of a DCV challenge. In this case, Cloudflare customers were unaffected.

Another time, one of the Certificate Authorities that we use found that they were renewing certificates based on validation tokens that did not comply with the CA/B Forum standards. This caused them to invoke a mass revocation, impacting about five thousand Cloudflare-managed domains. We worked with our customers and the CA to issue new certificates before the revocation, resulting in minimal impact.

We understand that mistakes happen, and we have been lucky enough that as these issues have come up, our engineering teams were able to mitigate quickly so that no customers were impacted. But that’s not enough: our systems need to be future-proof so that a revocation of 45 million certificates will have no impact on our customers. With backup certificates, we’ll be ready for a mass re-issuance, no matter the scale.

To be resilient against mass revocations initiated by our CAs, we are going to issue every backup certificate from a different CA than the primary certificate. This will add a layer of protection if one of our CAs will have to invoke a mass revocation — something that when initiated, is a ticking time bomb.

Challenges when Renewing Certificates

Scale: With great power, comes great responsibility

When the Heartbleed vulnerability was exposed, we had to re-issue about 100,000 certificates. At the time, this wasn’t a challenge for Cloudflare. Now, we are responsible for tens of millions of certificates. Even if our systems are able to handle this scale, we rely on our Certificate Authority partners to be able to handle it as well. In the case of an emergency, we don’t want to rely on systems that we do not control. That’s why it’s important for us to issue the certificates ahead of time, so that during a disaster, all we need to worry about is getting the backup certificates deployed.

Manual intervention for completing DCV

Another challenge that comes with re-issuing certificates is Domain Control Validation (DCV). DCV is a check used to validate the ownership of a domain before a Certificate Authority can issue a certificate for it. When customers onboard to Cloudflare, they can either delegate Cloudflare to be their DNS provider, or they can choose to use Cloudflare as a proxy while maintaining their current DNS provider.

When Cloudflare acts as the DNS provider for a domain, we can add Domain Control Validation (DCV) records on our customer’s behalf. This makes the certificate issuance and renewal process much simpler.

Domains that don’t use Cloudflare as their DNS provider — we call them partial zones — have to rely on other methods for completing DCV. When those domains proxy their traffic through us, we can complete HTTP DCV on their behalf, serving the HTTP DCV token from our Edge. However, customers that want their certificate issued before proxying their traffic need to manually complete DCV. In an event where Cloudflare has to re-issue thousands or millions of certificates, but cannot complete DCV on behalf of the customer, manual intervention will be required. While completing DCV is not an arduous task, it’s not something that we should rely on our customers to do in an emergency, when they have a small time frame, with high risk involved.

This is where backup certificates come into play. From now on, every certificate issuance will fire two orders: one for a certificate from the primary CA and one for the backup certificate. When we can complete the DCV on behalf of the customer, we will do so for both CAs.

Today, we’re only issuing backup certificates for domains that use Cloudflare as an Authoritative DNS provider. In the future, we’ll order backup certificates for partial zones. That means that for backup certificates for which we are unable to complete DCV, we will give customers the corresponding DCV records to get the certificate issued.

Backup Certificates Deployment Plan

We are happy to announce that Cloudflare has started deploying backup certificates on Universal Certificate orders for Free customers that use Cloudflare as an Authoritative DNS provider. We have been slowly ramping up the number of backup certificate orders and in the next few weeks, we expect every new Universal certificate pack order initiated on a Free, Pro, or Biz account to include a backup certificate, wrapped with a different key and issued from a different CA than the primary certificate.

At the end of April we will start issuing backup certificates for our Enterprise customers. If you’re an Enterprise customer and have any questions about backup certificates, please reach out to your Account Team.

Next Up: Backup Certificates for All

Today, Universal certificates make up 72% of the certificates in our pipeline. But we want full coverage! That’s why our team will continue building out our backup certificates pipeline to support Advanced Certificates and SSL for SaaS certificates. In the future, we will also issue backup certificates for certificates that our customers upload themselves, so they can have a backup they can rely on.

In addition, we will continue to improve our pipeline to make the deployment of backup certificates instantaneous — leaving our customers secure and online in an emergency.

At Cloudflare, our mission is to help build a better Internet. With backup certificates, we’re helping build a secure, reliable Internet that’s ready for any disaster. Interested in helping us out? We’re hiring.

The collective thoughts of the interwebz