In the fast-paced world of software development, maintaining comprehensive documentation often falls to the bottom of priority lists in favor of delivering functionality. Amazon Q Developer’s /doc agent changes this equation by automating README generation and updates. With this tool, the variable of time spent producing documentation is reduced to the point that it’s no longer a burden to the detriment of functionality.
The /doc agent leverages generative AI to analyze your codebase and generate comprehensive documentation. Additionally, the agent respects your .gitignore file and excludes files you don’t want to be included in documentation review.
Solution Overview: As an example, imagine a cloud infrastructure team at a technology consultancy had been working for weeks on their AWS DataSync project. The solution they built provided an elegant CDK implementation that automated data transfer between Amazon S3 buckets using AWS DataSync. The lead engineer had just finished implementing the final IAM role configurations when the product manager requested comprehensive documentation for the next day’s client handoff meeting. The team realized this would typically take hours of focused work. Instead, they decided to try Amazon Q Developer /doc agent.
Open your IDE with the Amazon Q extension installed
Click the Amazon Q icon to open the chat panel
Enter /doc to start the documentation process
Select your documentation task:
Create a new README
Update an existing README with recent code changes
Figure 1 – Entering /doc to start the documentation process.
Example: Creating a New README:
For projects without documentation, simply select: Create a README. It will confirm the project you are creating the README for.
Figure 2 – Select the Create a README option.
Once you verify the folder and select yes, the agent begins creating the README document for the folder. Here are the steps it works through: scanning the source files, summarizing the source files, and generating the documentation.
Figure 3 – Verify the folder and select yes.
When the document is created, you can preview the README file. The agent then presents you with the ability to either accept the changes or request modifications before implementation.
Figure 4 – Preview the created README file.
If you choose to accept, the README file is added to your project.
Figure 5 – Accept the changes so the README is added to your project folder.
Example: Updating Documentation with Code Changes
When your code evolves, you can keep the documentation synchronized by using /doc. The agent will review your recent code modifications and suggest appropriate documentation updates.
Figure 6 – Select Update an existing README to make changes to a README file.
Then you can describe the changes you want the agent to make to your README file.
Figure 7 – Describe changes to your README files.
For targeted documentation updates, you can provide specific instructions:
Figure 8 – Verify the folder and select yes.
Once you’ve made the changes, the agent asks you to verify them by selecting yes.
Figure 9 – Verify the changes and select yes.
Advanced Documentation Management
Multi-step Documentation Refinement:
Figure 10 – Multi-step Documentation Refinement.
Amazon Q Developer /doc agent allows for iterative improvement of your documentation through feedback loops. After generating initial documentation, you can:
Review the generated content for gaps or inaccuracies
Provide specific feedback to refine particular sections
Request additional sections on complex topics
Gradually build comprehensive documentation through multiple iterations
This iterative approach is particularly valuable for complex projects where documentation needs to evolve alongside the codebase.
Documentation for Specific Components
For modular projects, you can create targeted documentation at different levels:
Root-level README for project overview
Component-level READMEs for specific modules
Service-level documentation for microservices
API documentation for interfaces
By combining these documentation levels, you can maintain a hierarchical documentation structure that remains manageable and specific.
Handling Documentation Inheritance
Figure 11 – Handling Documentation Inheritance.
When working with derived or extended codebases:
Generate base documentation for the parent project
Create specialized documentation for extensions
Cross-reference related documentation to maintain consistency
Use the /doc agent to update specific sections when inheritance patterns change
Documentation Syncing Strategy
Figure 12 – Documentation Syncing Strategy.
For teams working on rapidly evolving projects:
Establish a documentation update schedule aligned with sprints
Assign documentation reviews as part of code review processes
Use /doc to generate change summaries after significant updates
Implement a verification process to ensure generated documentation accurately reflects code changes
Best Practices for /doc Agent
To improve results from documentation generation with Amazon Q Developer, follow these best practices:
Optimize repository size: Amazon Q Developer supports documentation generation across your codebase, accommodating projects up to the specified size limits. While documentation for larger repositories may require additional processing time and could provide more generalized results, you have the option to request documentation for specific subsets of code or individual files to receive more detailed insights.
Maintain high-quality code: The quality of documentation Amazon Q Developer generates improves significantly when your code is well-commented and organized, has meaningful naming conventions for programming entities, and follows standard coding conventions.
Be specific with change requests: When requesting specific README changes in natural language, choose to update an existing README and select the option to make a specific change. After initial documentation generation, you can request additional modifications by describing exactly what updates you want.
Craft effective change descriptions: When describing desired updates, include:
Specific sections you want to modify
Exact content you want to add or remove
Particular issues that need correcting
How project functionality should be reflected in the README
References to content available in your codebase.
Understand system limitations: Amazon Q Developer doesn’t have access to private or internal platforms and might lack knowledge of third-party tools, specialized software, or custom tooling in your code. Content requiring this knowledge won’t be documented automatically. In these cases, you’ll need to manually edit the README to include information Amazon Q Developer cannot generate.
Documentation Quotas and Limitations
When working with Amazon Q Developer /doc agent, be aware of these important constraints:
Document generations per task: There’s a limit to the number of feedback iterations allowed per documentation session. This quota resets each time you start a new documentation task.
File filtering: Amazon Q Developer filters out files or folders defined in your .gitignore file. This helps streamline the documentation process by focusing only on relevant code files.
Conclusion
Amazon Q Developer /doc agent transforms the documentation process from a tedious chore to an automated, efficient workflow. By generating and maintaining READMEs based on your actual code, it ensures documentation remains accurate and up-to-date without consuming precious development time.
As part of Amazon Q Developer’s free tier, the /doc agent is readily available to integrate into your development process. Start using it today to improve your project documentation and enhance team collaboration.
It is almost the end of Developer Week and we haven’t talked about containers: until now. As some of you may know, we’ve been working on a container platform behind the scenes for some time.
In late June, we plan to release Containers in open beta, and today we’ll give you a sneak peek at what makes it unique.
Workers are the simplest way to ship software around the world with little overhead. But sometimes you need to do more. You might want to:
Run user-generated code in any language
Execute a CLI tool that needs a full Linux environment
Use several gigabytes of memory or multiple CPU cores
Port an existing application from AWS, GCP, or Azure without a major rewrite
Cloudflare Containers let you do all of that while being simple, scalable, and global.
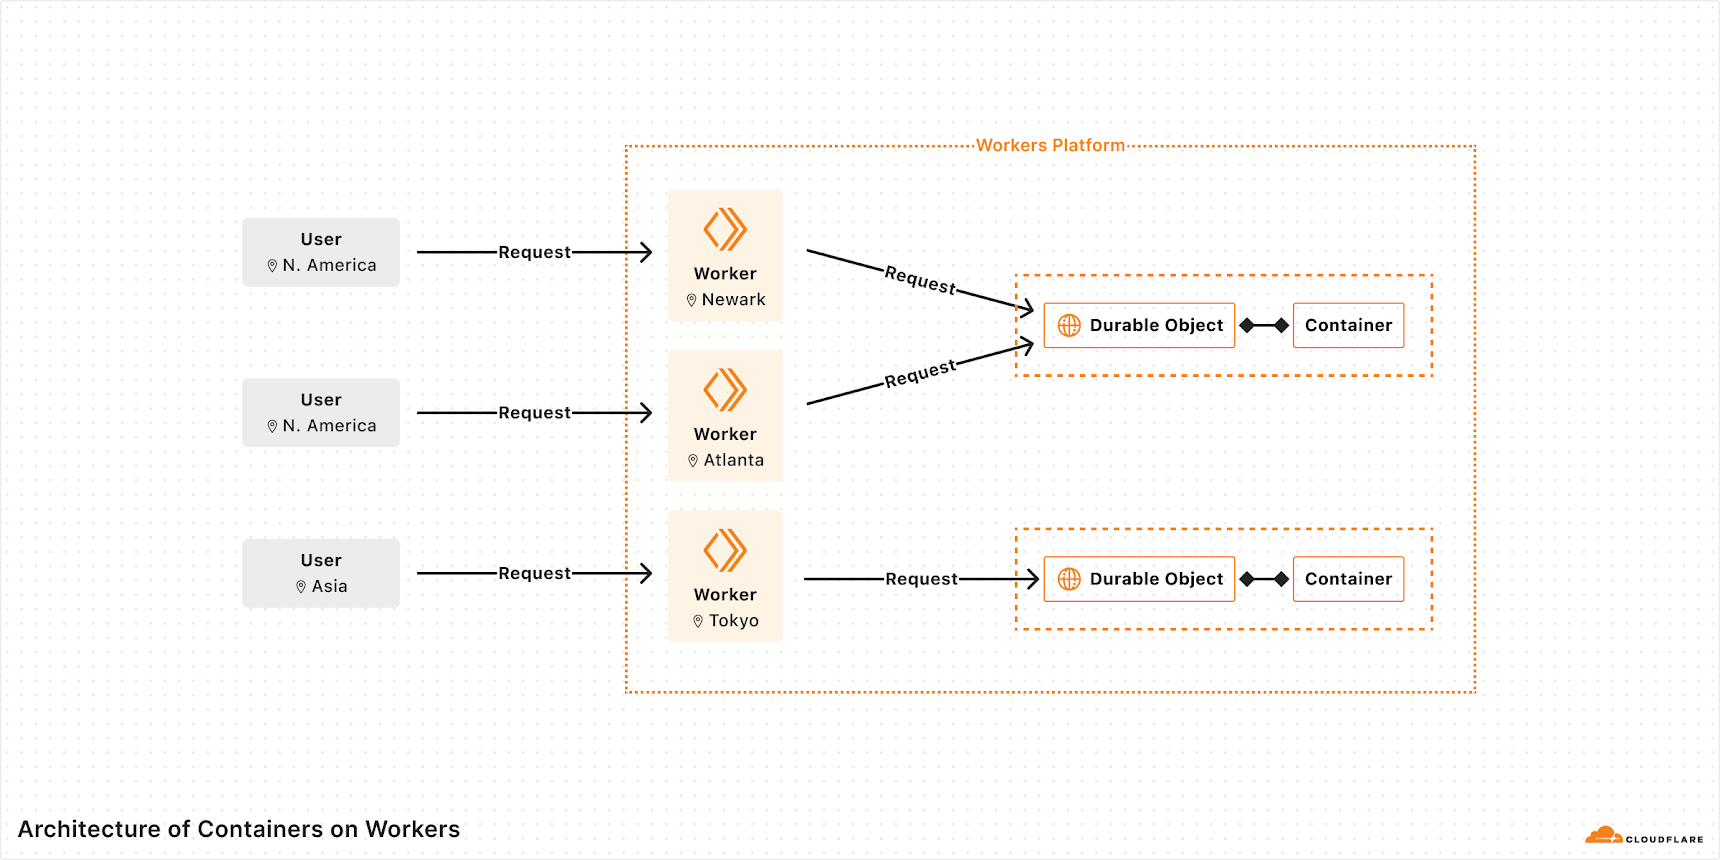
Through a deep integration with Workers and an architecture built on Durable Objects, Workers can be your:
API Gateway: Letting you control routing, authentication, caching, and rate-limiting before requests reach a container
Service Mesh: Creating private connections between containers with a programmable routing layer
Orchestrator: Allowing you to write custom scheduling, scaling, and health checking logic for your containers
Instead of having to deploy new services, write custom Kubernetes operators, or wade through control plane configuration to extend the platform, you just write code.
Let’s see what it looks like.
Deploying different application types
A stateful workload: executing AI-generated code
First, let’s take a look at a stateful example.
Imagine you are building a platform where end-users can run code generated by an LLM. This code is untrusted, so each user needs their own secure sandbox. Additionally, you want users to be able to run multiple requests in sequence, potentially writing to local files or saving in-memory state.
To do this, you need to create a container on-demand for each user session, then route subsequent requests to that container. Here’s how you can accomplish this:
First, you write some basic Wrangler config, then you route requests to containers via your Worker:
import { Container } from "cloudflare:workers";

export default {
  async fetch(request, env) {
    const url = new URL(request.url);

    if (url.pathname.startsWith("/execute-code")) {
      const { sessionId, messages } = await request.json();
      // pass in prompt to get the code from Llama 4
      const codeToExecute = await env.AI.run("@cf/meta/llama-4-scout-17b-16e-instruct", { messages });

// get a different container for each user session
      const id = env.CODE_EXECUTOR.idFromName(sessionId);
      const sandbox = env.CODE_EXECUTOR.get(id);

// execute a request on the container
      return sandbox.fetch("/execute-code", { method: "POST", body: codeToExecute });
    }

    // ... rest of Worker ...
  },
};

// define your container using the Container class from cloudflare:workers
export class CodeExecutor extends Container {
defaultPort = 8080;
sleepAfter = "1m";
}
Then, deploy your code with a single command: wrangler deploy. This builds your container image, pushes it to Cloudflare’s registry, readies containers to boot quickly across the globe, and deploys your Worker.
$ wrangler deploy
That’s it.
How does it work?
Your Worker creates and starts up containers on-demand. Each time you call env.CODE_EXECUTOR.get(id) with a unique ID, it sends requests to a unique container instance. The container will automatically boot on the first fetch, then put itself to sleep after a configurable timeout, in this case 1 minute. You only pay for the time that the container is actively running.
When you request a new container, we boot one in a Cloudflare location near the incoming request. This means that low-latency workloads are well-served no matter the region. Cloudflare takes care of all the pre-warming and caching so you don’t have to think about it.
This allows each user to run code in their own secure environment.
Stateless and global: FFmpeg everywhere
Stateless and autoscaling applications work equally well on Cloudflare Containers.
Imagine you want to run a container that takes a video file and turns it into an animated GIF using FFmpeg. Unlike the previous example, any container can serve any request, but you still don’t want to send bytes across an ocean and back unnecessarily. So, ideally the app can be deployed everywhere.
To do this, you declare a container in Wrangler config and turn on autoscaling. This specific configuration ensures that one instance is always running and if CPU usage increases beyond 75% of capacity, additional instances are added:
To route requests, you just call env.GIF_MAKER.fetch and requests are automatically sent to the closest container:
import { Container } from "cloudflare:workers";

export class GifMaker extends Container {
  defaultPort: 1337,
}

export default {
  async fetch(request, env) {
    const url = new URL(request.url);

    if (url.pathname === "/make-gif") {
      return env.GIF_MAKER.fetch(request)
    }

    // ... rest of Worker ...
  },
};
Going beyond the basics
From the examples above, you can see that getting a basic container service running on Workers just takes a few lines of config and a little Workers code. There’s no need to worry about capacity, artifact registries, regions, or scaling.
For more advanced use, we’ve designed Cloudflare Containers to run on top of Durable Objects and work in tandem with Workers. Let’s take a look at the underlying architecture and see some of the advanced use cases it enables.
Durable Objects as programmable sidecars
Routing to containers is enabled using Durable Objects under the hood. In the examples above, the Container class from cloudflare:workers just wraps a container-enabled Durable Object and provides helper methods for common patterns. In the rest of this post, we’ll look at examples using Durable Objects directly, as this should shed light on the platform’s underlying design.
Each Durable Object acts as a programmable sidecar that can proxy requests to the container and manages its lifecycle. This allows you to control and extend your containers in ways that are hard on other platforms.
You can manually start, stop, and execute commands on a specific container by calling RPC methods on its Durable Object, which now has a new object at this.ctx.container:
class MyContainer extends DurableObject {
	// these RPC methods are callable from a Worker
        async customBoot(entrypoint, envVars) {
	            this.ctx.container.start({ entrypoint, env: envVars });
        }

       async stopContainer() {
                   const SIGTERM = 15;
	           this.ctx.container.signal(SIGTERM);
        }

        async startBackupScript() {
	            await this.ctx.container.exec(["./backup"]);
        }
}
You can also monitor your container and run hooks in response to Container status changes.
For instance, say you have a CI job that runs builds in a Container. You want to post a message to a Queue based on the exit status. You can easily program this behavior:
And lastly, if you have state that needs to be loaded into a container each time it runs, you can use status hooks to persist state from the container before it sleeps and to reload state into the container after it starts:
import { startAndWaitForPort } from "./helpers"

class MyContainer extends DurableObject {
  constructor(ctx, env) {
    super(ctx, env)
    this.ctx.blockConcurrencyWhile(async () => {
      this.ctx.storage.sql.exec('CREATE TABLE IF NOT EXISTS state (value TEXT)');
      this.ctx.storage.sql.exec('INSERT INTO state (value) SELECT '' WHERE NOT EXISTS (SELECT * FROM state)');
      await startAndWaitForPort(this.ctx.container, 8080);
      await this.setupContainer();
      this.ctx.container.monitor().then(this.onContainerExit);
    });
  }

  async setupContainer() {
    const initialState = this.ctx.storage.sql.exec('SELECT * FROM state LIMIT 1').one().value;
    return this.ctx.container
      .getTcpPort(8080)
      .fetch("http://container/state", { body: initialState, method: 'POST' });
  }

  async onContainerExit() {
    const response = await this.ctx.container
      .getTcpPort(8080)
      .fetch('http://container/state');
    const newState = await response.text();
    this.ctx.storage.sql.exec('UPDATE state SET value = ?', newState);
  }
}
Building around your Containers with Workers
Not only do Durable Objects allow you to have fine-grained control over the Container lifecycle, the whole Workers platform allows you to extend routing and scheduling behavior as you see fit.
Using Workers as an API gateway
Workers provide programmable ingress logic from over 300 locations around the world. In this sense, they provide similar functionality to an API gateway.
For instance, let’s say you want to route requests to a different version of a container based on information in a header. This is accomplished in a few lines of code:
Or you want to rate limit and authenticate requests to the container:
async fetch(request, env) {
  const url = new URL(request.url);

  if (url.pathname.startsWith('/api/')) {
    const token = request.headers.get("token");

    const isAuthenticated = await authenticateRequest(token);
    if (!isAuthenticated) {
      return new Response("Not authenticated", { status: 401 });
    }

    const { withinRateLimit } = await env.MY_RATE_LIMITER.limit({ key: token });
    if (!withinRateLimit) {
      return new Response("Rate limit exceeded for token", { status: 429 });
    }

    return env.MY_APP.fetch(request);
  }
  // ...
}
Using Workers as a service mesh
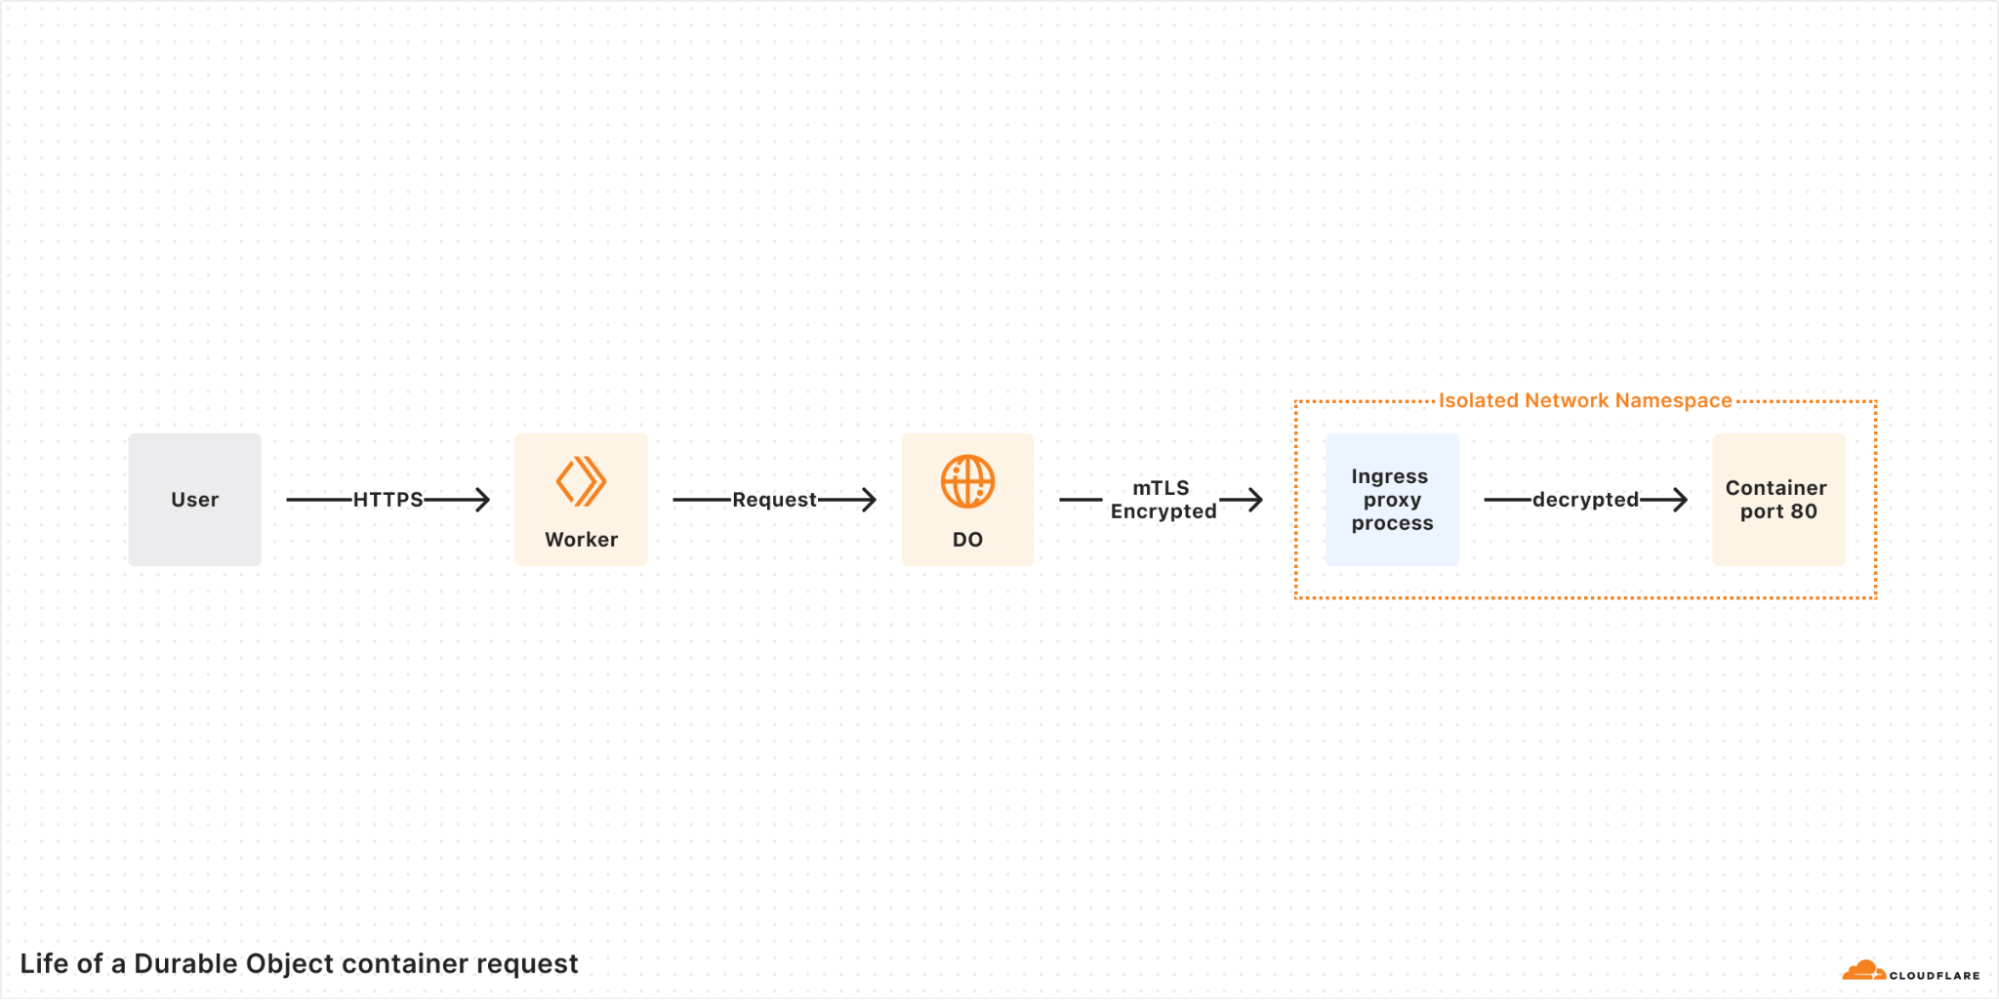
By default, Containers are private and can only be accessed via Workers, which can connect to one of many container ports. From within the container, you can expose a plain HTTP port, but requests will still be encrypted from the end user to the moment we send the data to the container’s TCP port in the host. Due to the communication being relayed through the Cloudflare network, the container does not need to set up TLS certificates to have secure connections in its open ports.
You can connect to the container through a WebSocket from the client too. See this repository for a full example of using Websockets.
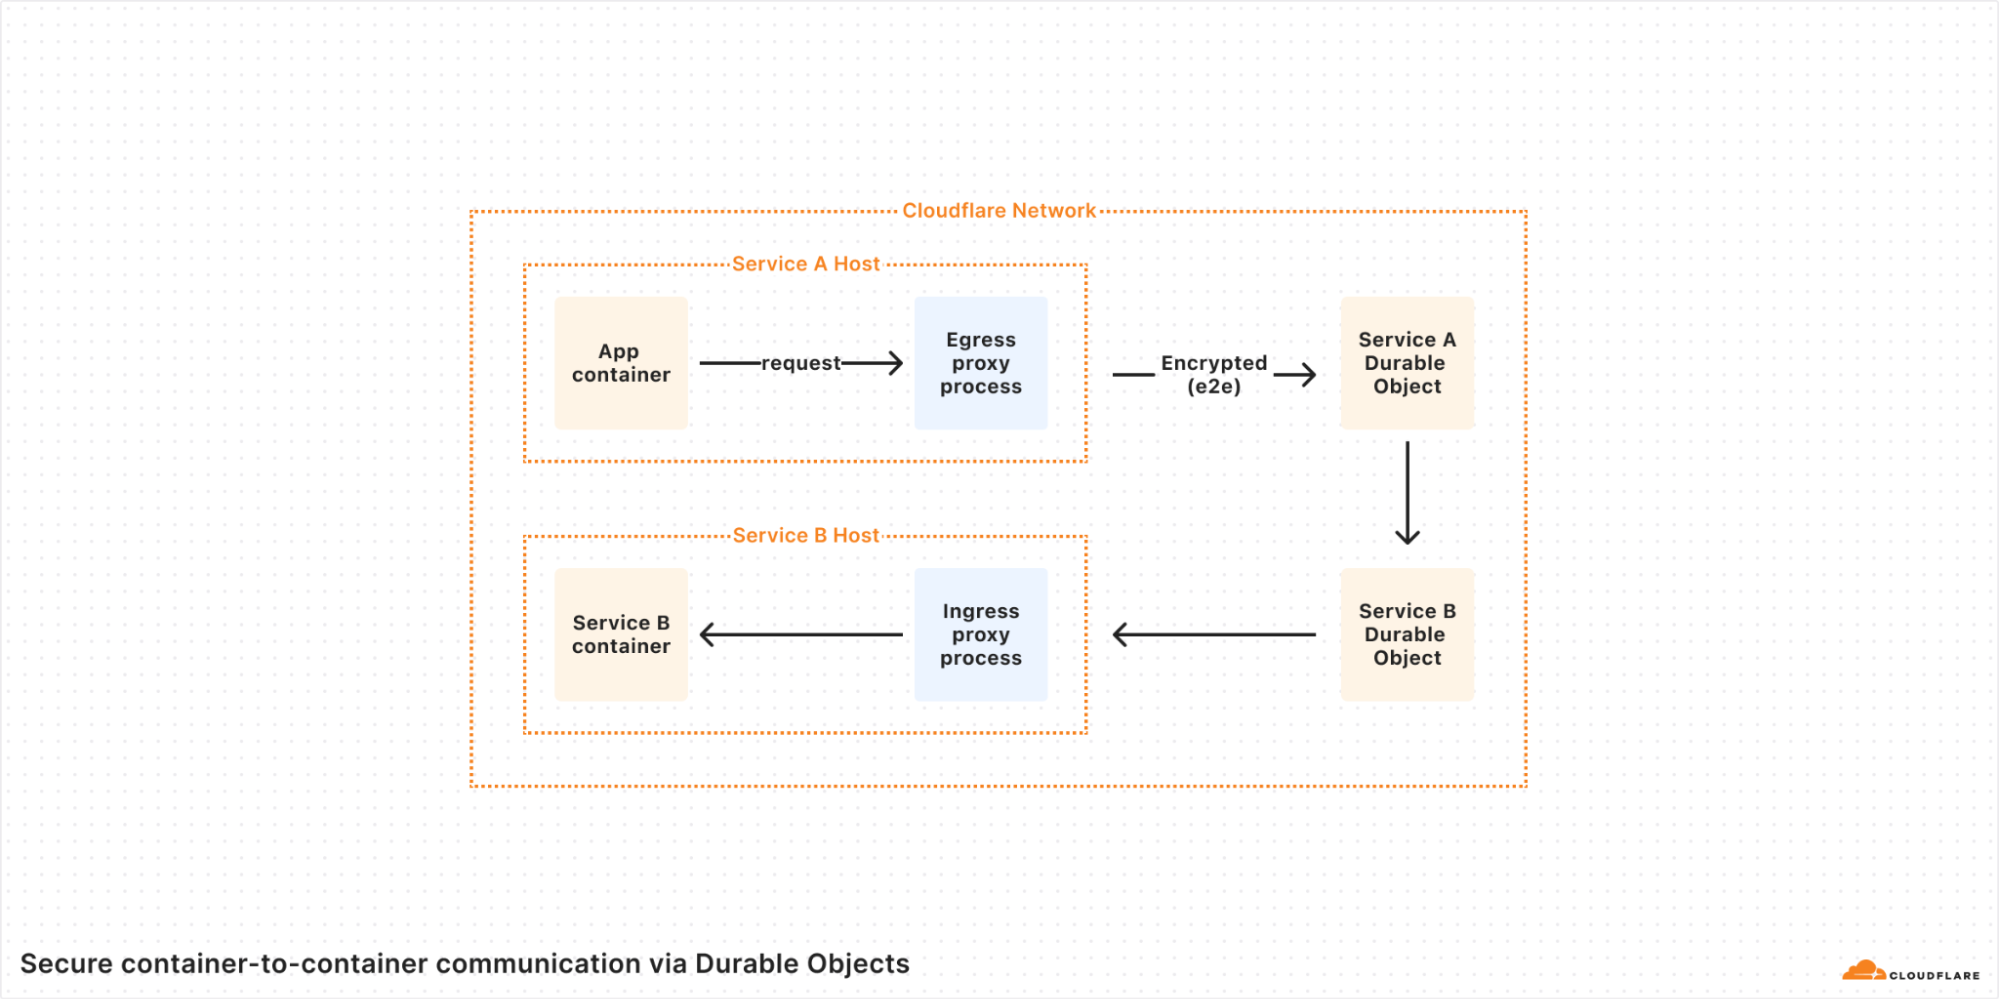
Just as the Durable Object can act as proxy to the container, it can act as a proxy from the container as well. When setting up a container, you can toggle Internet access off and ensure that outgoing requests pass through Workers.
// ... when starting the container...
this.ctx.container.start({
  workersAddress: '10.0.0.2:8080',
  enableInternet: false, // 'enableInternet' is false by default
});

// ... container requests to '10.0.0.2:8080' securely route to a different service...
override async onContainerRequest(request: Request) {
 const containerId = this.env.SUB_SERVICE.idFromName(request.headers['X-Account-Id']);
 return this.env.SUB_SERVICE.get(containerId).fetch(request);
}
You can ensure all traffic in and out of your container is secured and encrypted end to end without having to deal with networking yourself.
This allows you to protect and connect containers within Cloudflare’s network… or even when connecting to external private networks.
Using Workers as an orchestrator
You might require custom scheduling and scaling logic that goes beyond what Cloudflare provides out of the box.
We don’t want you having to manage complex chains of API calls or writing an operator to get the logic you need. Just write some Worker code.
For instance, imagine your containers have a long startup period that involves loading data from an external source. You need to pre-warm containers manually, and need control over the specific region to prewarm. Additionally, you need to set up manual health checks that are accessible via Workers. You’re able to achieve this fairly simply with Workers and Durable Objects.
import { Container, DurableObject } from "cloudflare:workers";

// A singleton Durable Object to manage and scale containers

class ContainerManager extends DurableObject {
  scale(region, instanceCount) {
    for (let i = 0; i < instanceCount; i++) {
      const containerId = env.CONTAINER.idFromName(`instance-${region}-${i}`);
      // spawns a new container with a location hint
      await env.CONTAINER.get(containerId, { locationHint: region }).start();
    }
  }

  async setHealthy(containerId, isHealthy) {
    await this.ctx.storage.put(containerId, isHealthy);
  }
}

// A Container class for the underlying compute

class MyContainer extends Container {
  defaultPort = 8080;

  async onContainerStart() {
    // run healthcheck every 500ms
    await this.scheduleEvery(0.5, 'healthcheck');
  }

  async healthcheck() {
    const manager = this.env.MANAGER.get(
      this.env.MANAGER.idFromName("manager")
    );
    const id = this.ctx.id.toString();

    await this.container.fetch("/_health")
      .then(() => manager.setHealthy(id, true))
      .catch(() => manager.setHealthy(id, false));
  }
}
The ContainerManager Durable Object exposes the scale RPC call, which you can call as needed with a region and instanceCount which scales up the number of active Container instances in a given region using a location hint. The this.schedule code executes a manually defined healthcheck method on the Container and tracks its state in the Manager for use by other logic in your system.
These building blocks let users handle complex scheduling logic themselves. For a more detailed example using standard Durable Objects, see this repository.
We are excited to see the patterns you come up with when orchestrating complex applications built with containers, and trust that between Workers and Durable Objects, you’ll have the tools you need.
Integrating with more of Cloudflare’s Developer Platform
Let’s finish up by taking a quick look at how you can integrate Containers with these two tools.
Running a short-lived job with Workflows & R2
You need to download a large file from R2, compress it, and upload it. You want to ensure that this succeeds, but don’t want to write retry logic and error handling yourself. Additionally, you don’t want to deal with rotating R2 API tokens or worry about network connections — it should be secure by default.
This is a perfect opportunity for a Workflow using Containers. The container can do the heavy lifting of compressing files, Workers can stream the data to and from R2, and the Workflow can ensure durable execution.
Lastly, imagine you have an AI agent that needs to spin up cloud infrastructure (you like to live dangerously). To do this, you want to use Terraform, but since it’s run from the command line, you can’t run it on Workers.
By defining a tool, you can enable your Agent to run the shell commands from a container:
// Make tools that call to a container from an agent

const createExternalResources = tool({
  description: "runs Terraform in a container to create resources",
  parameters: z.object({ sessionId: z.number(), config: z.string() }),
  execute: async ({ sessionId, config }) => {
    return this.env.TERRAFORM_RUNNER.get(sessionId).applyConfig(config);
  },
});

// Expose RPC Methods that call to the container

class TerraformRunner extends DurableObject {
  async applyConfig(config) {
    await this.ctx.container.getTcpPort(8080).fetch(APPLY_URL, {
      method: 'POST',
      body: JSON.stringify({ config }),
    });
  }

  // ...rest of DO...
}
Containers are so much more powerful when combined with other tools. Workers make it easy to do so in a secure and simple way.
Pay for what you use and use the right tool
The deep integration between Workers and Containers also makes it easy to pick the right tool for the job with regards to cost.
With Cloudflare Containers, you only pay for what you use. Charges start when a request is sent to the container or it is manually started. Charges stop after the container goes to sleep, which can happen automatically after a configurable timeout. This makes it easy to scale to zero, and allows you to get high utilization even with highly-variable traffic.
Containers are billed for every 10ms that they are actively running at the following rates:
Memory: $0.0000025 per GB-second
CPU: $0.000020 per vCPU-second
Disk $0.00000007 per GB-second
After 1 TB of free data transfer per month, egress from a Container will be priced per-region. We’ll be working out the details between now and the beta, and will be launching with clear, transparent pricing across all dimensions so you know where you stand.
Workers are lighter weight than containers and save you money by not charging when waiting on I/O. This means that if you can, running on a Worker helps you save on cost. Luckily, on Cloudflare it is easy to route requests to the right tool.
Cost comparison
Comparing containers and functions services on paper is always going to be an apples to oranges exercise, and results can vary so much depending on use case. But to share a real example of our own, a year ago when Cloudflare acquired Baselime, Baselime was a heavy user of AWS Lambda. By moving to Cloudflare, they lowered their cloud compute bill by 80%.
Below we wanted to share one representative example that compares costs for an application that uses both containers and serverless functions together. It’d be easy for us to come up with a contrived example that uses containers sub-optimally on another platform, for the wrong types of workloads. We won’t do that here. We know that navigating cloud costs can be challenging, and that cost is a critical part of deciding what type of compute to use for which pieces of your application.
In the example below, we’ll compare Cloudflare Containers + Workers against Google Cloud Run, a very well-regarded container platform that we’ve been impressed by.
Example application
Imagine that you run an application that serves 50 million requests per month, and each request consumes an average 500 ms of wall-time. Requests to this application are not all the same though — half the requests require a container, and the other half can be served just using serverless functions.
Requests per month
Wall-time (duration)
Compute required
Cloudflare
Google Cloud
25 million
500ms
Container + serverless functions
Containers + Workers
Google Cloud Run + Google Cloud Run Functions
25 million
500ms
Serverless functions
Workers
Google Cloud Run Functions
Container pricing
On both Cloud Run and Cloudflare Containers, a container can serve multiple requests. On some platforms, such as AWS Lambda, each container instance is limited to a single request, pushing cost up significantly as request count grows. In this scenario, 50 requests can run simultaneously on a container with 4 GB memory and half of a vCPU. This means that to serve 25 million requests of 500ms each, we need 625,000 seconds worth of compute
In this example, traffic is bursty and we want to avoid paying for idle-time, so we’ll use Cloud Run’s request-based pricing.
Price per vCPU second
Price per GB-second of memory
Price per 1m requests
Monthly Price for Compute + Requests
Cloudflare Containers
$0.000020
$0.0000025
$0.30
$20.00
Google Cloud Run
$0.000024
$0.0000025
$0.40
$23.75
* Comparison does not include free tiers for either provider and uses a single Tier 1 GCP region
Compute pricing for both platforms are comparable. But as we showed earlier in this post, Containers on Cloudflare run anywhere, on-demand, without configuring and managing regions. Each container has a programmable sidecar with its own database, backed by Durable Objects. It’s the depth of integration with the rest of the platform that makes containers on Cloudflare uniquely programmable.
Function pricing
The other requests can be served with less compute, and code written in JavaScript, TypeScript, Python or Rust, so we’ll use Workers and Cloud Run Functions.
These 25 million requests also run for 500 ms each, and each request spends 480 ms waiting on I/O. This means that Workers will only charge for 20 ms of “CPU-time”, the time that the Worker actually spends using compute. This ratio of low CPU time to high wall time is extremely common when building AI apps that make inference requests, or even when just building REST APIs and other business logic. Most time is spent waiting on I/O. Based on our data, we typically see Workers use less than 5 ms of CPU time per request vs seconds of wall time (waiting on APIs or I/O).
The Cloud Run Function will use an instance with 0.083 vCPU and 128 MB memory and charge on both CPU-s and GiB-s for the full 500 ms of wall-time.
Total Price for “wall-time”
Total Price for “CPU-time”
Total Price for Compute + Requests
Cloudflare Workers
N/A
$0.83
$8.33
Google Cloud Run Functions
$1.44
N/A
$11.44
* Comparison does not include free tiers and uses a single Tier 1 GCP region.
This comparison assumes you have configured Google Cloud Run Functions with a max of 20 concurrent requests per instance. On Google Cloud Run Functions, the maximum number of concurrent requests an instance can handle varies based on the efficiency of your function, and your own tolerance for tail latency that can be introduced by traffic spikes.
Workers automatically scale horizontally, don’t require you to configure concurrency settings (and hope to get it right), and can run in over 300 locations.
A holistic view of costs
The most important cost metric is the total cost of developing and running an application. And the only way to get the best results is to use the right compute for the job. So the question boils down to friction and integration. How easily can you integrate the ideal building blocks together?
As more and more software makes use of generative AI, and makes inference requests to LLMs, modern applications must communicate and integrate with a myriad of services. Most systems are increasingly real-time and chatty, often holding open long-lived connections, performing tasks in parallel. Running an instance of an application in a VM or container and calling it a day might have worked 10 years ago, but when we talk to developers in 2025, they are most often bringing many forms of compute to the table for particular use cases.
This shows the importance of picking a platform where you can seamlessly shift traffic from one source of compute to another. If you want to rate-limit, serve server-side rendered pages, API responses and static assets, handle authentication and authorization, make inference requests to AI models, run core business logic via Workflows, or ingest streaming data, just handle the request in Workers. Save the heavier compute only for where it is actually the only option. With Cloudflare Workers and Containers, this is as simple as an if-else statement in your Worker. This makes it easy to pick the right tool for the job.
Coming June 2025
We are collecting feedback and putting the finishing touches on our APIs now, and will release the open beta to the public in late June 2025.
From day one of building Cloudflare Workers, it’s been our goal to build an integrated platform, where Cloudflare products work together as a system, rather than just as a collection of separate products. We’ve taken this same approach with Containers, and aim to make Cloudflare not only the best place to deploy containers across the globe, but the best place to deploy the types of complete applications that developers are building, that use containers in tandem with serverless functions, Workflows, Agents, and much more.
We’re excited to get this into your hands soon. Stay on the lookout this summer.
With quick access to flexible infrastructure and innovative AI tools, startups are able to deploy production-ready applications with speed and efficiency. Cloudflare plays a pivotal role for countless applications, empowering founders and engineering teams to build, scale, and accelerate their innovations with ease — and without the burden of technical overhead. And when applicable, initiatives like our Startup Program and Workers Launchpad offer the tooling and resources that further fuel these ambitious projects.
Cloudflare recently announcedAI agents, allowing developers to leverage Cloudflare to deploy agents to complete autonomous tasks. We’re already seeing some great examples of startups leveraging Cloudflare as their platform of choice to invest in building their agent infrastructure. Read on to see how a few up-and-coming startups are building their AI agent platforms, powered by Cloudflare.
Lamatic AI built a scalable AI agent platform using Workers for Platform
Founded in 2023, Lamatic.ai empowers SaaS startups to seamlessly integrate intelligent AI agents into their products. Lamatic.ai simplifies the deployment of AI agents by offering a fully managed lifecycle with scalability and security in mind. SaaS providers have been leveraging Lamatic to replatform their AI workflows via a no-code visual builder to reduce technical debt and ship products faster. Designed for high availability, scalability, and low latency, Lamatic’s architecture enables developers to build AI-driven applications that remain performant under heavy load. After acquiring a high amount of users in a short amount of time on Product Hunt, Lamatic identified there was real interest to solve complex problems with AI Agents, and the team knew they needed to build a solution with scalability and performance in mind.
Cloudflare plays a key role in supporting Lamatic’s growth. Powered by Cloudflare Workers, Lamatic ensures requests process closer to end users, minimizing latency while offloading computational strain from centralized servers. In just a few months, Lamatic.ai has efficiently scaled to over three million serverless requests per month, supporting over 1,000 customers — all managed by a lean three-person team.
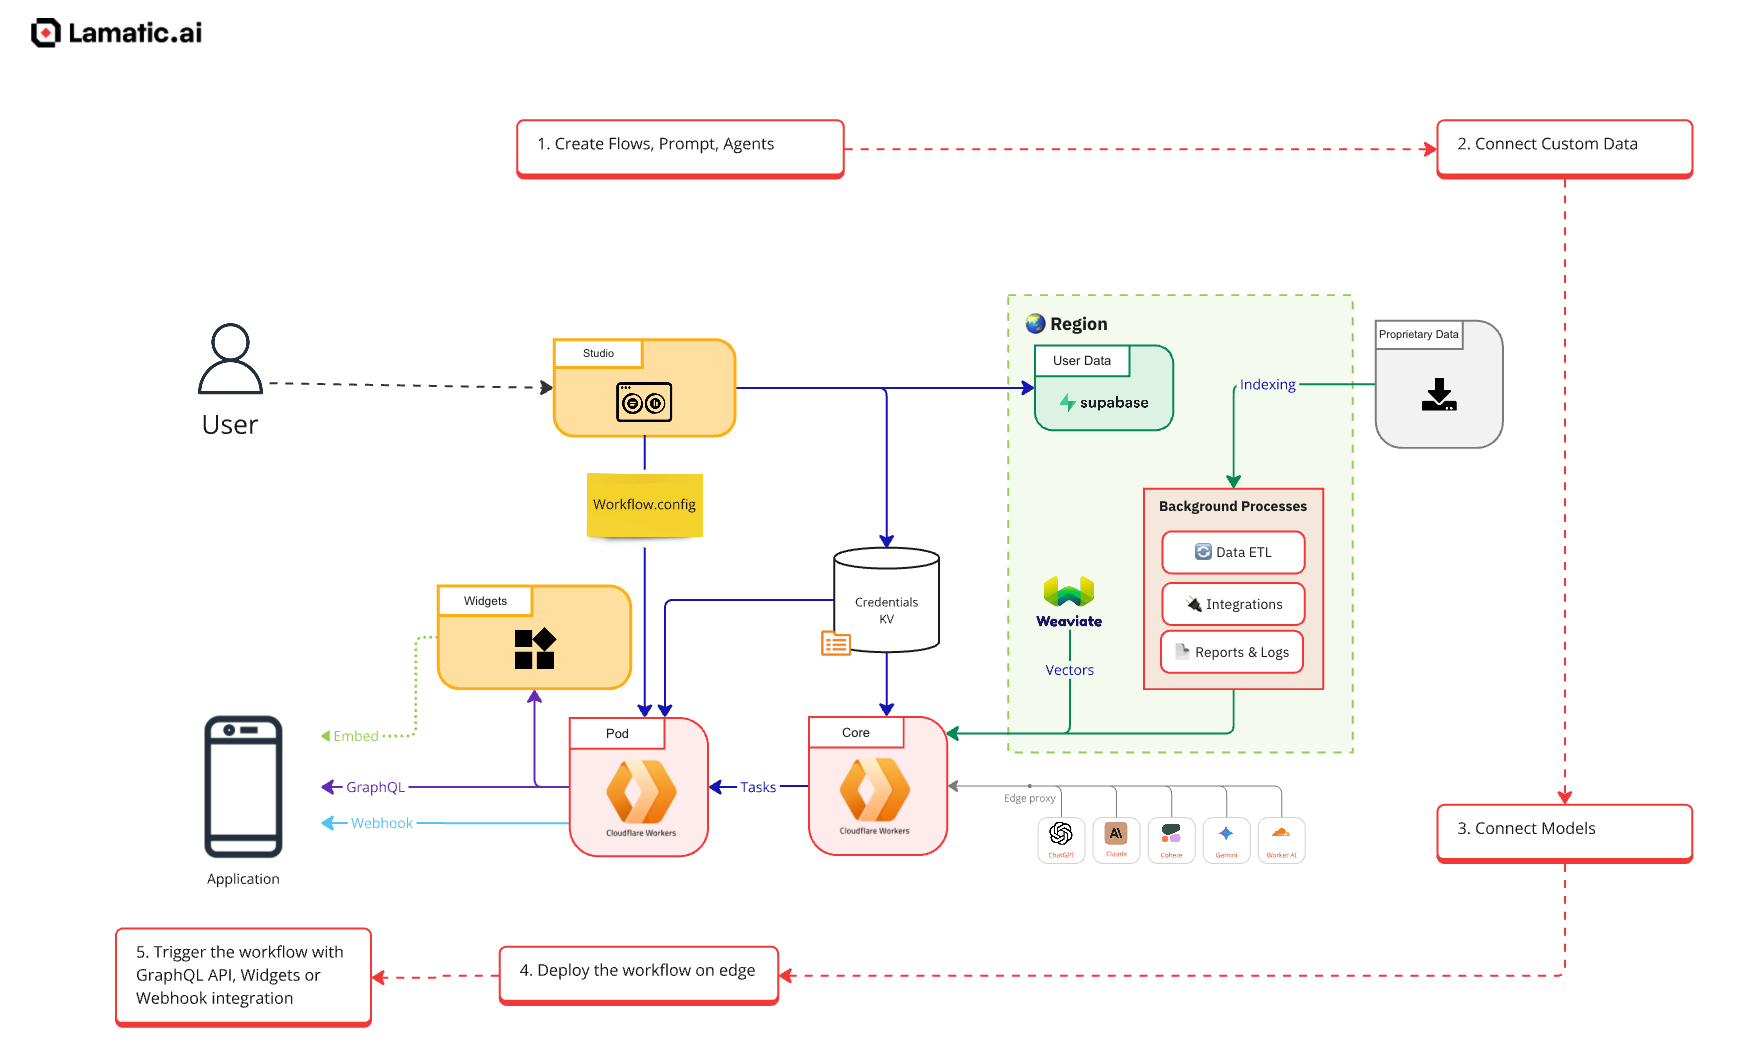
Customers design their Agent Flows through a no-code visual builder, which generates an interoperable YAML configuration. Sensitive credentials such as API keys and model access tokens are securely encrypted and stored in Workers KV, ensuring they are only decrypted at runtime for enhanced security. All YAML configurations are then compiled into a Workers-compatible JavaScript bundle. When a project is deployed, Lamatic orchestrates critical components like sync jobs for scheduled data ETL operations and incoming webhooks to handle event-driven workflows via Cloudflare Queues. Once deployed, the project is fully operational as a Cloudflare Worker with an exposed API endpoint, allowing customers to integrate AI-powered automation directly into their applications with minimal friction.
To scale out their platform, Lamatic.ai built their architecture isolating serverless and AI logic on a per-customer basis. Rather than batching requests into a centralized cluster, Lamatic.ai distributes workloads across Cloudflare’s global network, ensuring each customer and endpoint is served by its own Worker executing dedicated logic. This per-customer deployment model — enabled by Workers for Platforms— allows Lamatic.ai to deliver customer-specific serverless functions at scale, and reduces technical overhead as they onboard additional customers. Each customer gets a dedicated Worker whose request and rate limits are enabled based on their level of subscription.
Beyond request processing, Lamatic uses Cloudflare Workers KV as a distributed config store to ensure high availability and security. All values are encrypted at rest with AES-256-GCM and decrypted only at runtime, keeping operations both secure and low-latency. Tokens and user credentials are encrypted and stored in the database and KV.
To further enhance performance, Cloudflare Queues plays a key role in orchestrating task completion. Lamatic uses Queues to offload work from Workers requests, and handle tasks such as webhooks and coordinating distributed processes, both essential for maintaining system consistency and reliability at scale. While Workers handle sync requests at point of execution, longer running jobs process via Queues. For example, during a scheduled ETL sync, new data records generated are stored as a message queue on Cloudflare Pub/Sub. A consumer Worker collects these messages and makes an API request to the pod using the Workers Queue. The consumer Worker consumes more messages as each queue is finished processing.
Another example of where this has been optimal is for managing AI workflows. Many AI workflows involve concurrent requests to multiple data sources, Queues streamlines data processing and efficiently feeds information into customers’ Retrieval Augmented Generation (RAG) workflows. This approach smooths out workload spikes, reduces bottlenecks, and ensures that AI agents can reliably aggregate and process data without delays.
Beyond this, Lamatic.ai offers Workers AI as one of the support inference providers that customers can use across their platform. Customers can choose to run one of the many open source models hosted on Workers AI, depending on their use case (chatbot, image generation, voice, etc.). Together, these layers solve the challenges of scaling AI agents by handling high volumes of data, maintaining low-latency responses, and ensuring robust security. With Cloudflare’s infrastructure as its backbone, Lamatic.ai has built a resilient and high-performing platform that meets the rigorous demands of modern AI applications, making it an ideal choice for startups embedding AI-driven features into their products.
Skyward AI automates compliance using AI agents with Durable Objects and agents
Skyward AI is transforming compliance operations by leveraging Cloudflare’s serverless computing capabilities to build AI-driven compliance agents that streamline critical tasks like evidence collection, real-time risk analysis, and policy updates. Compliance teams in fintech, supply chain, and other highly regulated industries use these AI Agents to extract and organize evidence, provide real-time recommendations, and orchestrate policy and procedural updates automatically. By handling document parsing, risk monitoring, and policy enforcement, these AI Agents reduce the risk of human error while allowing compliance professionals to focus on high-value tasks.
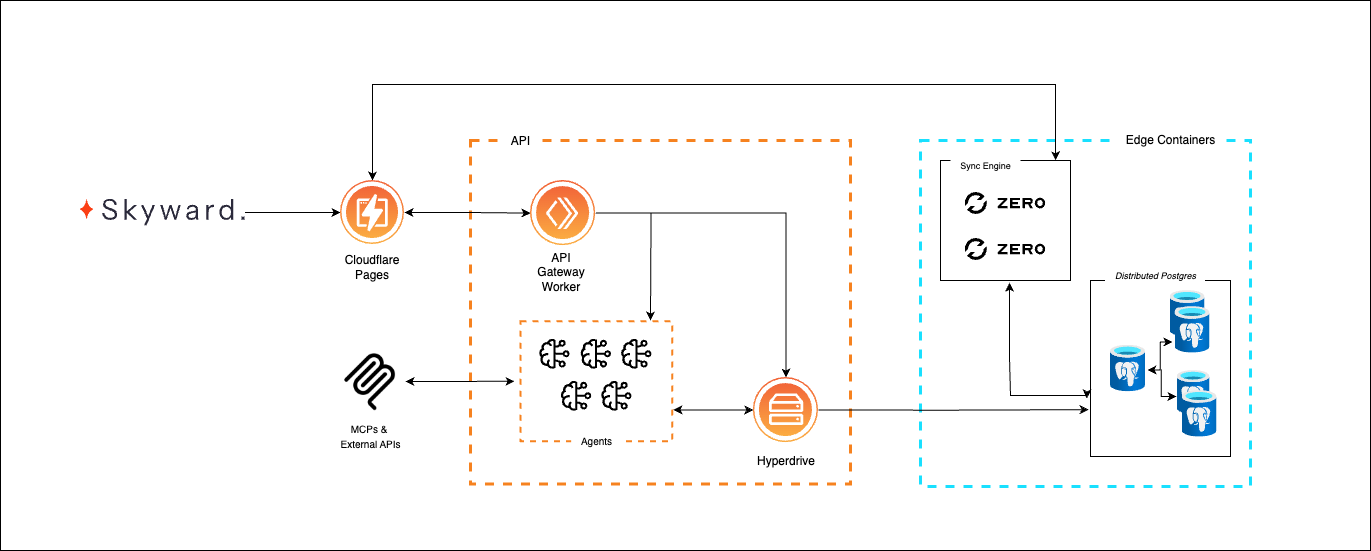
Skyward has built an AI agents platform designed with a serverless-first approach, avoiding the constraints of centralized cloud computing. To achieve this, the company leverages Cloudflare’s Developer Platform to create and maintain a highly responsive and scalable infrastructure. Workers handle incoming requests like chat inputs, compliance checks, or authentication, and route them efficiently across multiple geographies. Skyward initially built their AI agents infrastructure using Durable Objects,Workflows and JavaScript-native RPC for AI coordination, but has recently transitioned to Cloudflare’s new AI agents framework. Given that agents provides a framework for building and orchestrating AI agents, the migration has helped Skyward abstract the need to manage Durable Objects manually, significantly reducing time spent on managing these tools. While this release is fairly recent, the transition has helped simplify the way that agents communicate, but it also preserved the benefits of their original design like data privacy, isolation, and concurrency management. This has also made it easier to provide real-time feedback and responses to their end users.
Skyward optimizes real-time compliance automation by achieving sub-100 ms response times for AI agent queries. Workloads are structured to minimize unnecessary network round-trips, and a sync-engine approach proactively preloads and pushes data to clients, delivering a highly responsive user experience. To proxy AI inference, Skyward uses AI Gateway to provide observability into usage, performance, and costs across multiple vendors, improving their AI operational efficiency. Leveraging Cloudflare’s serverless Developer Platform has allowed Skyward to simplify their architecture while supporting global availability, avoiding the need for Kubernetes clusters or complex locking mechanisms. The team also avoids the burden of managing regional deployments, as Cloudflare’s multi-region support ensures consistent performance worldwide without added operational complexity.
State management is a critical component to execute agentic workflows. Each compliance session runs within a dedicated Durable Object, which keeps relevant data close to the execution layer. This setup minimizes database round-trips and ensures that tasks like Anti-Money Laundering (AML) checks, Know Your Business (KYB) validation, and document processing remain efficient. Once a compliance session is complete, the system summarizes and stores the relevant information in Postgres and R2, optimizing memory usage without requiring persistent cloud infrastructure.
To balance low-latency operations with long-term storage, Skyward employs a multi-layered data management strategy. The Skyward team, using Hyperdrive, has been able to reduce query latency by nearly 50%, allowing compliance teams to receive immediate feedback. At the company’s core, Skyward’s goal is to offer a platform that is “streamlined for compliance teams”. The team maintains that a speedy feedback loop ensures end customers get the data and responses needed to act. Whether there’s one agent or hundreds of agents processing tasks in parallel, Hyperdrive ensures that database requests to assets like extensive company documentation (i.e. regulations, policies, procedures, internal documents), complex regulatory knowledge graphs, and on-demand context information for conversational workflows are all as performant as possible.
Durable Objects facilitate real-time session state, ensuring AI agents function smoothly without complex locking mechanisms. For larger compliance-related documents, such as legal PDFs and archived data, Cloudflare R2 provides long-term storage, ensuring only frequently accessed information remains readily available. This approach enhances performance while keeping storage management efficient and cost-effective.
Security and scalability remain priorities for compliance-focused AI applications. Skyward enforces strict access controls, ensuring that only authorized users can access development and production environments. Each AI session maintains an auditable log of key events, user actions, and approvals, supporting the ability to export these insights for compliance and legal requirements. Because each agent is deployed in its own instance and has its own database, Skyward ensures that there is a detailed record of every required user, agent interaction, and auditing requirements. On top of this, the ability to deploy and scale globally with Cloudflare’s network has allowed Skyward to maintain consistent, high-performance operations across multiple regions without extensive infrastructure overhead.
Looking ahead, Skyward plans to further enhance AI agent responsiveness by running select models directly on Cloudflare Workers AI, reducing reliance on external inference providers. The team plans to further integrate Workers for Platforms in an effort to better isolate customer data and workflows, giving end users greater control over their compliance automation. As Cloudflare continues to evolve its AI capabilities, Skyward aims to push the boundaries of distributed AI compliance solutions, making regulatory adherence more automated, scalable, and secure.
Building on Cloudflare
We’re inspired by how startups like Lamatic AI and Skyward AI are building their AI agent platforms on Cloudflare. This kind of innovation is why we’re proud to see so many startups trust Cloudflare for a scalable, reliable, and efficient foundation.
We’re also thrilled to share that both Lamatic AI and Skyward AI have been invited to join Cloudflare’s upcoming Workers Launchpad Cohort #5. Speaking of Workers Launchpad, it’s been a few months since our last update — let’s take a look at what’s new.
Thank you to Workers Launchpad Cohort #4, and a warm welcome to Cohort #5
The Workers Launchpad team is blown away by what customers are demonstrating on the Developer Platform. Members of Cohort #4 presented at our bi-annual Demo Day. We had customers demonstrate what they’re building across a multitude of industries, including (of course) AI / ML, developer tools, 3D design, cloud infrastructure, adtech, media, and beyond. It’s incredibly encouraging to see what all these amazing companies are building on the Cloudflare network, and we look forward to continuing to partner with them throughout their startup journey.
Following the Demo Day for Workers Launchpad Cohort #4, we’ve seen the largest influx of applications from startups across the globe eager to join Cohort #5. This next wave of founders is pushing the boundaries of what’s possible, building in areas like AI agents, developer tooling, MCP, media, and beyond. With each new cohort, we’re continually inspired by the caliber of founding teams, the bold ideas they bring to life, and the real-world problems they’re tackling with technology.
Help us give some love and a warm welcome to the participants of Cohort #5:
We can’t wait to share more about what Cohort #5 achieves. Be sure to follow @CloudflareDev on X and join our Developer Discord server to hear updates on the cohorts.
If you’re developing your application on our Developer Platform, we’d love to learn how Cloudflare is powering your journey. Please share more about what you’re building, and our team will be sure to review your submission. And if you’re a startup and interested in joining Workers Launchpad, feel free to apply for Cohort 6 — applications are now open!
Today, we’re sharing a preview of a new feature that makes it easier to build cross-cloud apps: Workers VPC.
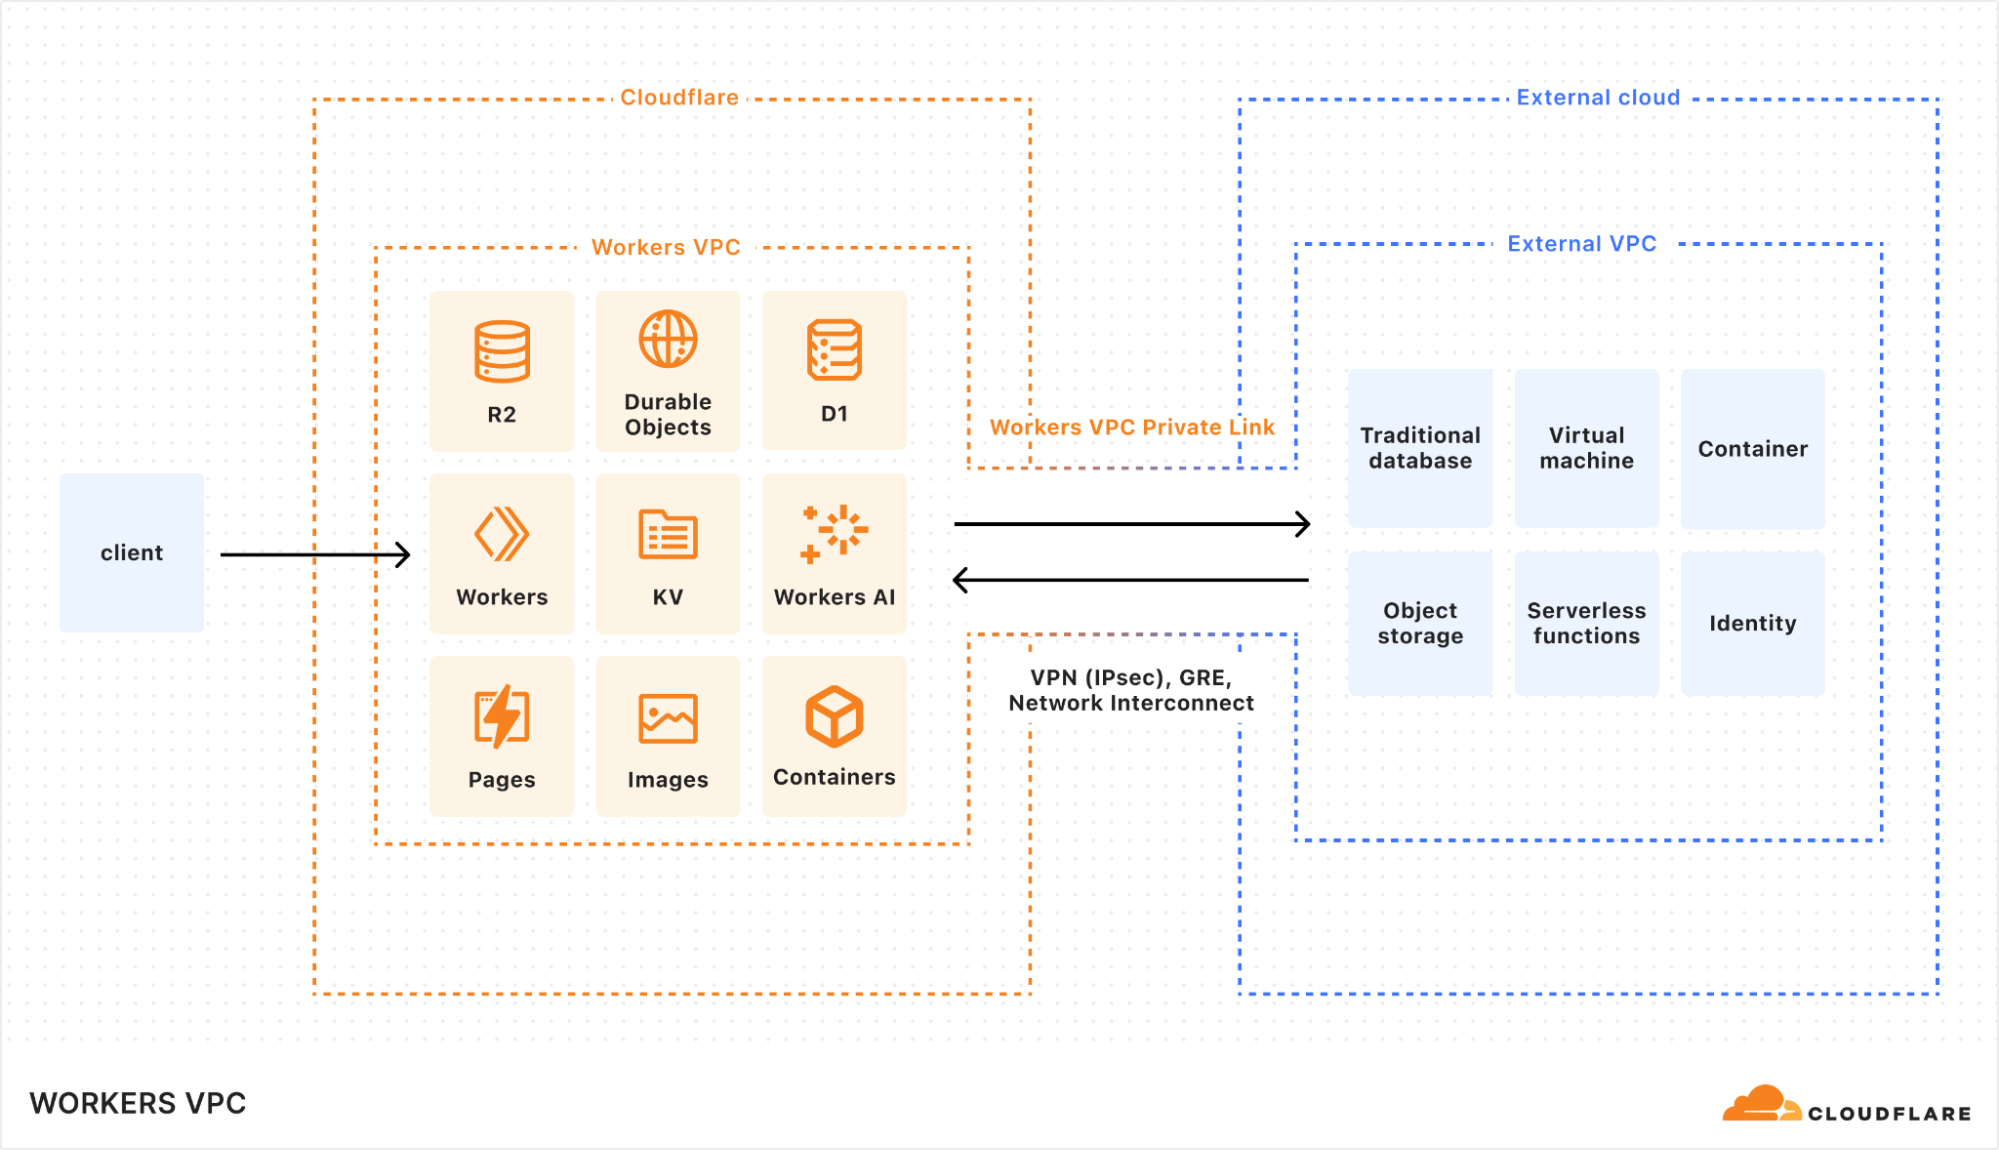
Workers VPC is our take on the traditional virtual private cloud (VPC), modernized for a network and compute that isn’t tied to a single cloud region. And we’re complementing it with Workers VPC Private Links to make building across clouds easier. Together, they introduce two new capabilities to Workers:
A way to group your apps’ resources on Cloudflare into isolated environments, where only resources within a Workers VPC can access one another, allowing you to secure and segment app-to-app traffic (a “Workers VPC”).
A way to connect a Workers VPC to a legacy VPC in a public or private cloud, enabling your Cloudflare resources to access your resources in private networks and vice versa, as if they were in a single VPC (the “Workers VPC Private Link”).
Workers VPC and Workers VPC Private Link enable bidirectional connectivity between Cloudflare and external clouds
When linked to an external VPC, Workers VPC makes the underlying resources directly addressable, so that application developers can think at the application layer, without dropping down to the network layer. Think of this like a unified VPC across clouds, with built-in service discovery.
We’re actively building Workers VPC on the foundation of our existing private networking products and expect to roll it out later in 2025. We wanted to share a preview of it early to get feedback and learn more about what you need.
Building private cross-cloud apps is hard
Developers are increasingly choosing Workers as their platform of choice, building rich, stateful applications on it. We’re way past Workers’ original edge use-cases: you’re modernizing more of your stack and moving more business logic on to Workers. You’re choosing Workers to build real-time collaboration applications that access your external databases, large scale applications that use your secured APIs, and Model Context Protocol (MCP) servers that expose your business logic to agents as close to your end users as possible.
Now, you’re running into the final barrier holding you back in external clouds: the VPC. Virtual private clouds provide you with peace of mind and security, but they’ve been cleverly designed to deliberately add mile-high barriers to building your apps on Workers. That’s the unspoken, vested interest behind getting you to use more legacy VPCs:it’s yet another way that captivity cloudshold your data and apps hostage and lock you in.
In conversation after conversation, you’ve told us “VPCs are a blocker”. We get it: your company policies mandate the VPC, and with good reason! So, to access private resources from Workers, you have to either 1) create new public APIs that perform authentication to provide secure access, or 2) set up and scale Cloudflare Tunnels and Zero Trust for each resource that you want to access. That’s a lot of hoops to jump through before you can even start building.
While we have the storage and compute options for you to build fully on Workers, we also understand that you won’t be moving your applications or your data overnight! But we think you should at least be free to choose Workers today to build modern applications, AI agents, and real-time global applications with your existing private APIs and databases. That’s why we’re building Workers VPC.
We’ve witnessed the pain of building around VPCs first hand. In 2024, we shipped support for private databases for Hyperdrive. This made it possible for you to connect to databases in an external VPC from Cloudflare Workers, using Cloudflare Tunnels as the underlying network solution. As a point-to-point solution, it’s been working great! But this solution has its limitations: managing and scaling a Cloudflare Tunnel for each resource in your external cloud isn’t sustainable for large, complex architectures.
We want to provide a dead-simple solution for you to unlock access to external cloud resources, in a manner that scales as you modernize more of your workloads with Workers. And we’re leveraging the experience we have in building Magic WAN and Magic Cloud Networking to make that possible.
So, we’re taking VPCs global with Workers VPC. And we’re letting you connect them to your legacy private networks with Workers VPC Private Links. Because we think you should be free to build secure, global, cross-cloud apps on Workers.
Global cross-cloud apps need a global VPC
Private networks are complex to set up, they span across many layers of abstraction, and entire teams are needed to manage them. There are few things as complex as managing architectures that have outgrown their original point-to-point network! So we knew we needed to provide a simple solution for isolated environments on our platform.
Workers VPCs are, by definition, virtual private clouds. That means that they allow you to define isolated environments of Workers and Developer Platform resources like R2, Workers KV, and D1 that have secure access to one another. Other resources in your Cloudflare account won’t have access to these — VPCs allow you to specify certain sets of resources that are associated with certain apps and ensure no cross-application access of resources happens.
Workers VPCs are the equivalent of the legacy VPC, re-envisioned for the Cloudflare Developer Platform. The main difference is how Workers VPCs are implemented under the hood: instead of being built on top of regional, IP-based networking, Workers VPCs are built for global scale with the Cloudflare network performing isolation of resources across all of its datacenters.
And as you would expect from traditional VPCs, Workers VPCs have networking capabilities that allow them to seamlessly integrate with traditional networks, enabling you to build cross-cloud apps that never leave the networks you trust. That’s where Workers VPC Private Links comes in.
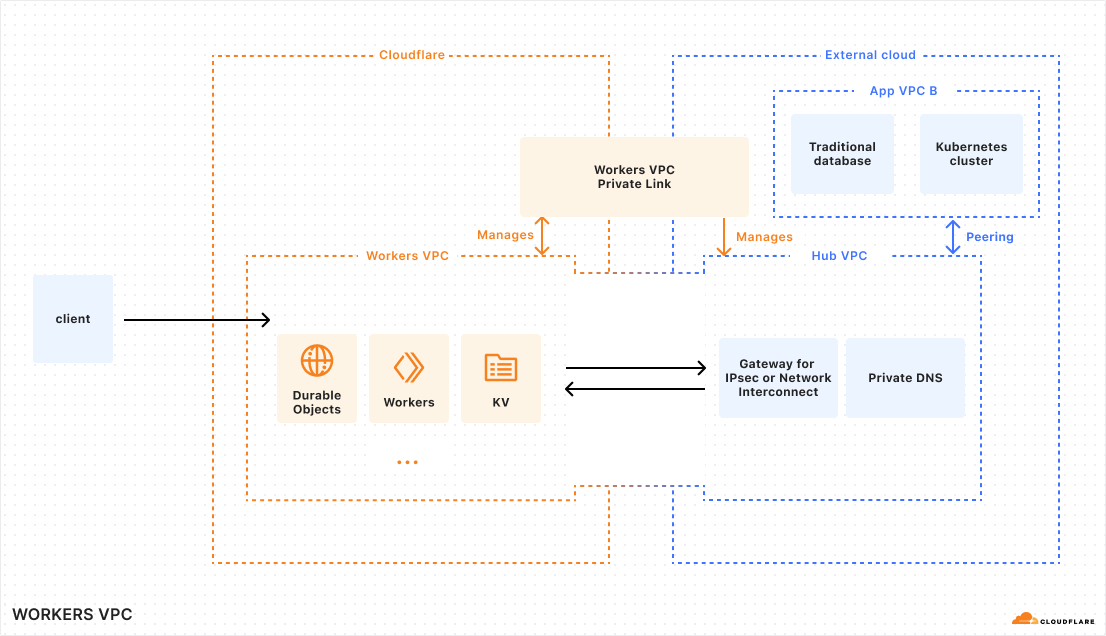
Like AWS PrivateLink and other VPC-to-VPC approaches, Workers VPC Private Links connect your Workers VPC to your external cloud using either standard tunnels over IPsec or Cloudflare Network Interconnect. When a Private Link is established, resources from either side can access one another directly, with nothing exposed over the public Internet, as if they were a single, connected VPC.
Workers VPC Private Link automatically provisions a gateway for IPsec tunnels or Cloudflare Network Interconnect and configures DNS for routing to Cloudflare resources
To make this possible, Workers VPC and Private Links work together to automatically provision and manage the resources in your external cloud. This establishes the connection between both networks and configures the resources required to make bidirectional routing possible. And, because we know some teams will want to maintain full responsibility over resource provisioning, Workers VPC Private Link can automatically provide you with Terraform scripts to provision external cloud resources that you can run yourself.
After the connection is made, Workers VPC will automatically detect the resources in your external VPC and make them available as bindings with unique IDs. Requests made through the Workers VPC resource binding will automatically be routed to your external VPC, where DNS resolution will occur (if you’re using hostname-accessed resources) and will be routed to the expected resource.
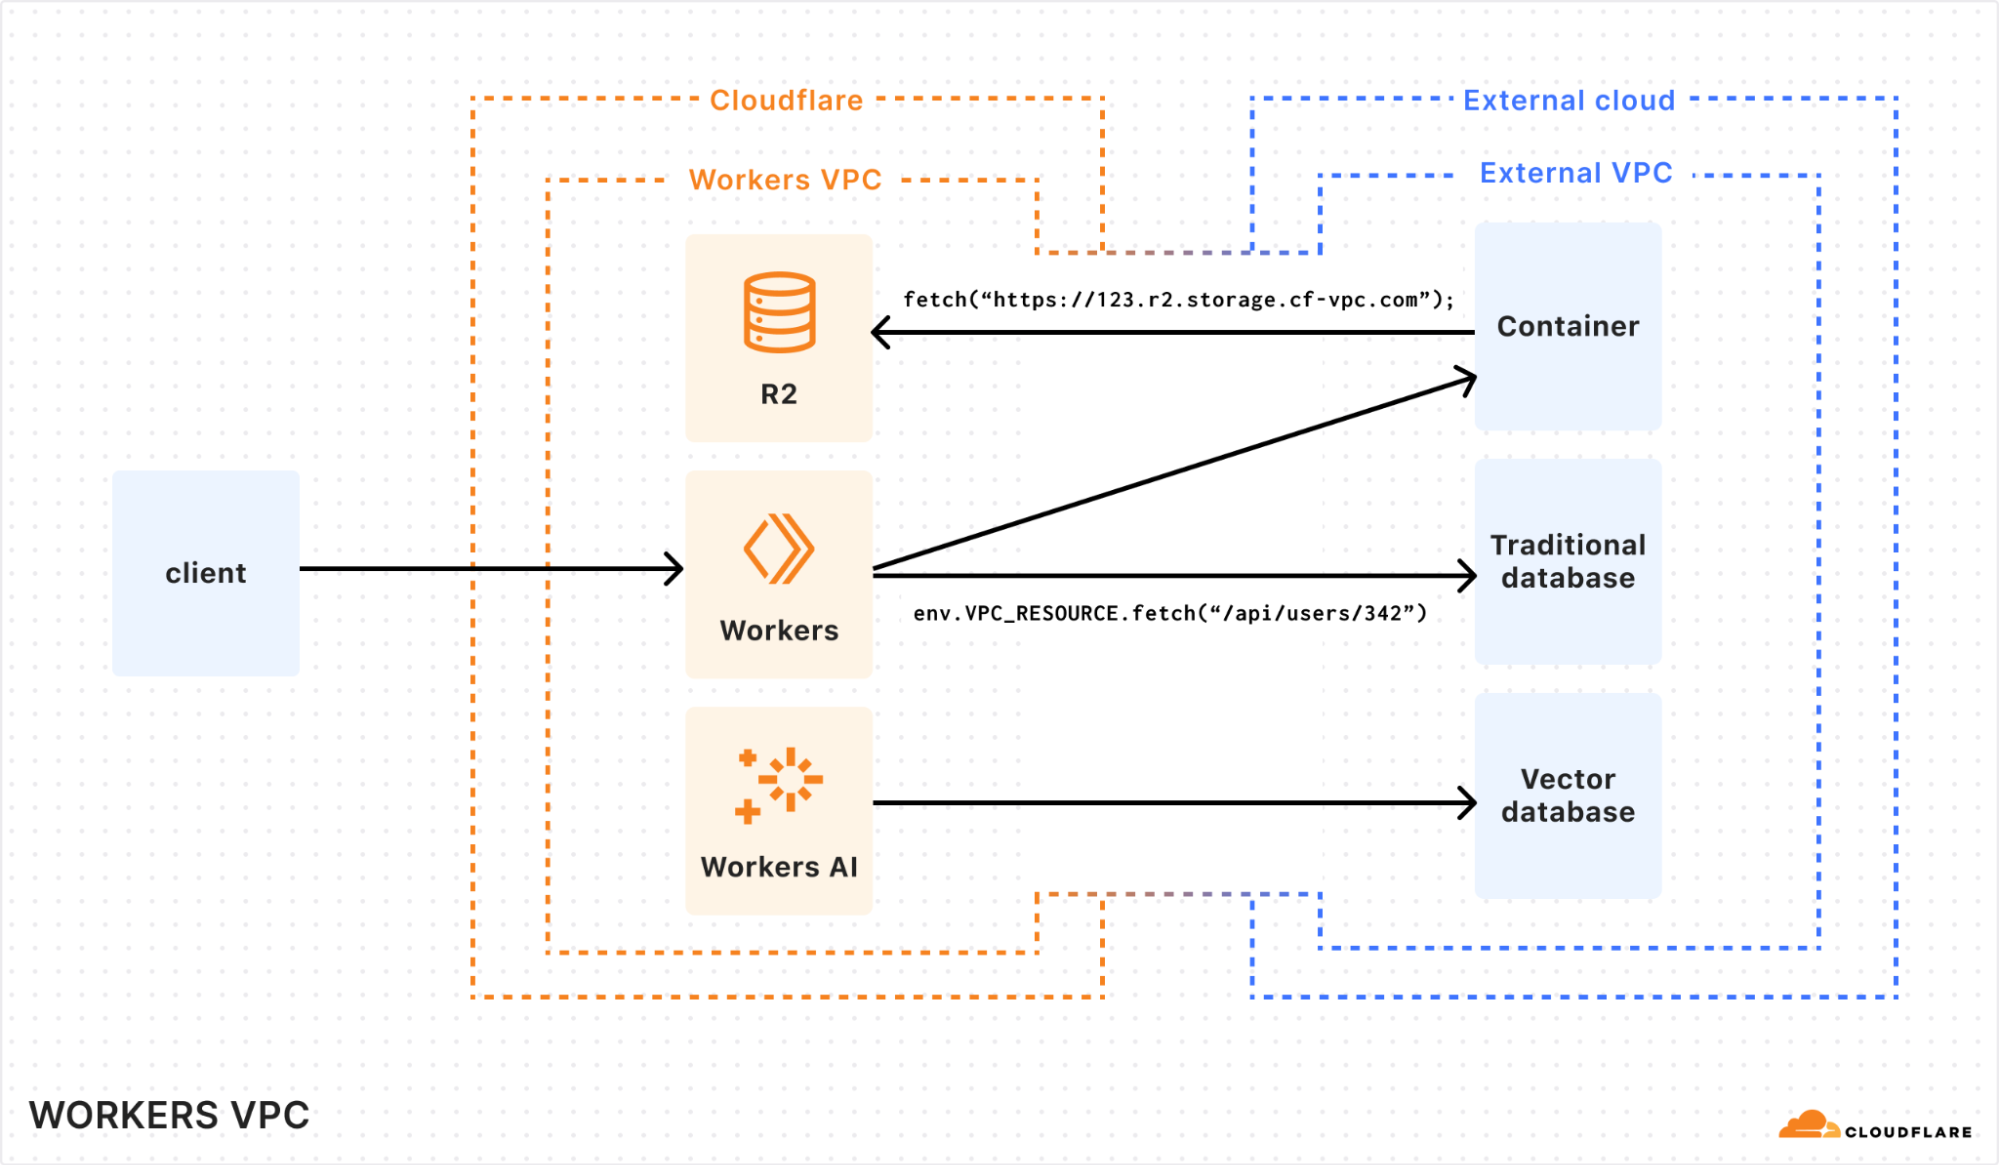
For example, connecting from Cloudflare Workers to a private API in an external VPC is just a matter of calling fetch() on a binding to a named Workers VPC resource:
Similarly, Cloudflare resources are accessible via a standardized URL that has been configured within a private DNS resource in your external cloud by Workers VPC Private Link. If you were attempting to access R2 objects from an API in your VPC, you would be able to make the request to the expected URL:
Best of all, since Workers VPC is built on our existing platform, it takes full advantage of our networking and routing capabilities to reduce egress fees and let you build global apps.
First, by supporting Cloudflare Network Interconnect as the underlying connection method, Workers VPC Private Links can help you lower your bandwidth costs by taking advantage of discounted external cloud egress pricing. Second, since Workers VPC is global by nature, your Workers and resources can be placed wherever needed to ensure optimal performance. For instance, with Workers’ Smart Placement, you can ensure that your Workers are automatically placed in a region closest to your external, regional VPC to maximize app performance.
An end-to-end connectivity cloud
Workers VPC unlocks huge swaths of your workloads that are currently locked into external clouds, without requiring you to expose those private resources to the public Internet to build on Workers. Here are real examples of applications that you’ve told us you’re looking forward to build on Workers with Workers VPC:
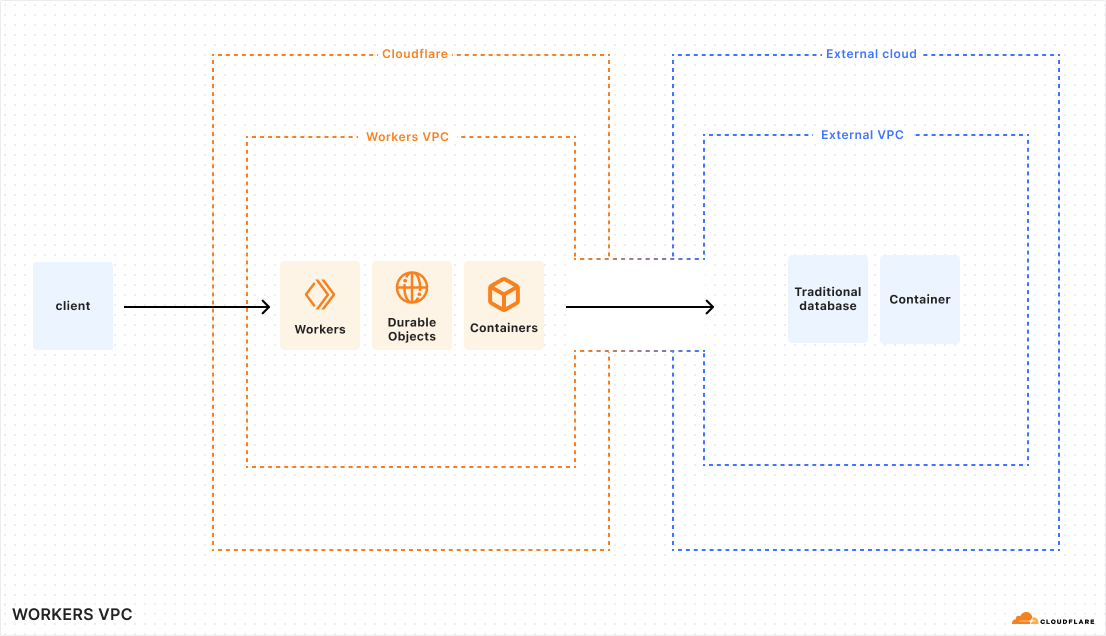
Sample architecture of real-time canvas application built on Workers and Durable Objects accessing a private database and container in an external VPC
Let’s say you’re trying to build a new feature for your application on Workers. You also want to add real-time collaboration to your app using Durable Objects. And you’re using Containers as well because you need to access FFmpeg for live video processing. In each scenario, you need a way to persist the state updates in your existing traditional database and access your existing APIs.
While in the past, you might have had to create a separate API just to handle update operations from Workers and Durable Objects, you can now directly access the traditional database and update the value directly with Workers VPC.
Same thing goes for Model Context Protocol (MCP) servers! If you’re building an MCP server on Workers, you may want to expose certain functionality that isn’t immediately available as a public API, especially if time to market is important. With Workers VPC, you can create new functionality directly in your MCP server that builds upon your private APIs or databases, enabling you to ship quickly and securely.
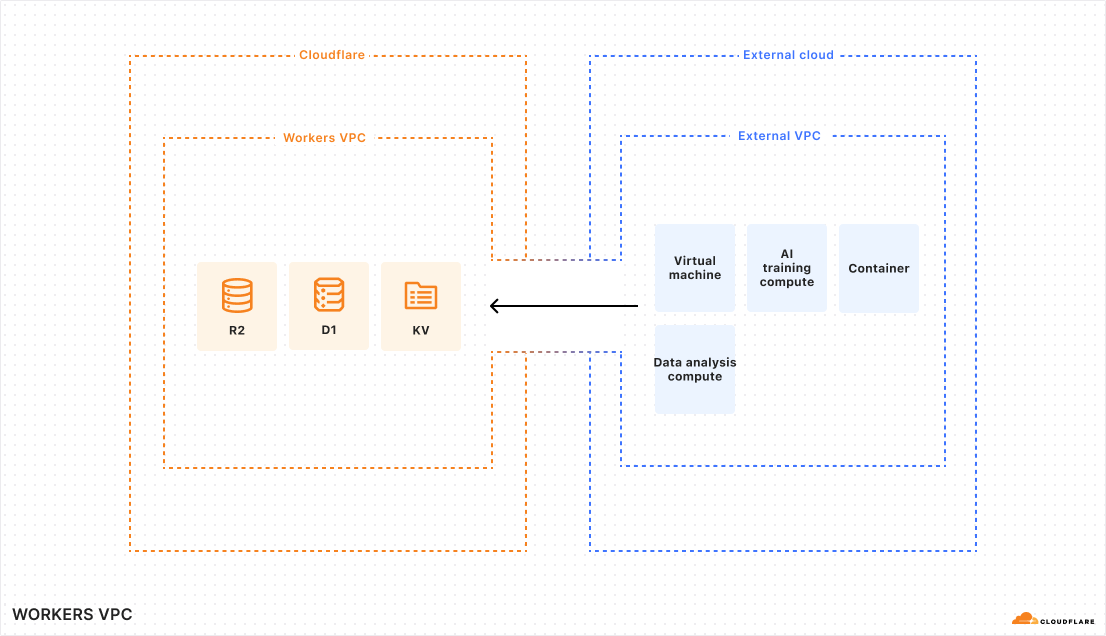
Sample architecture of external cloud resources accessing data from R2, D1, KV
Lots of development teams are landing more and more data on the Cloudflare Developer Platform, whether it is storing AI training data on R2 due to its zero-egress cost efficiency, application data in D1 with its horizontal sharding model, or configuration data in KV for its global single-digit millisecond read latencies.
Now, you need to provide a way to use the training data in R2 from your compute in your external cloud to train or fine-tune LLM models. Since you’re accessing user data, you need to use a private network because it’s mandated by your security teams. Likewise, you need to access user data and configuration data in D1 and KV for certain administrative or analytical tasks and you want to do so while avoiding the public Internet. Workers VPC enables direct, private routing from your external VPC to Cloudflare resources, with easily accessible hostnames from the automatically configured private DNS.
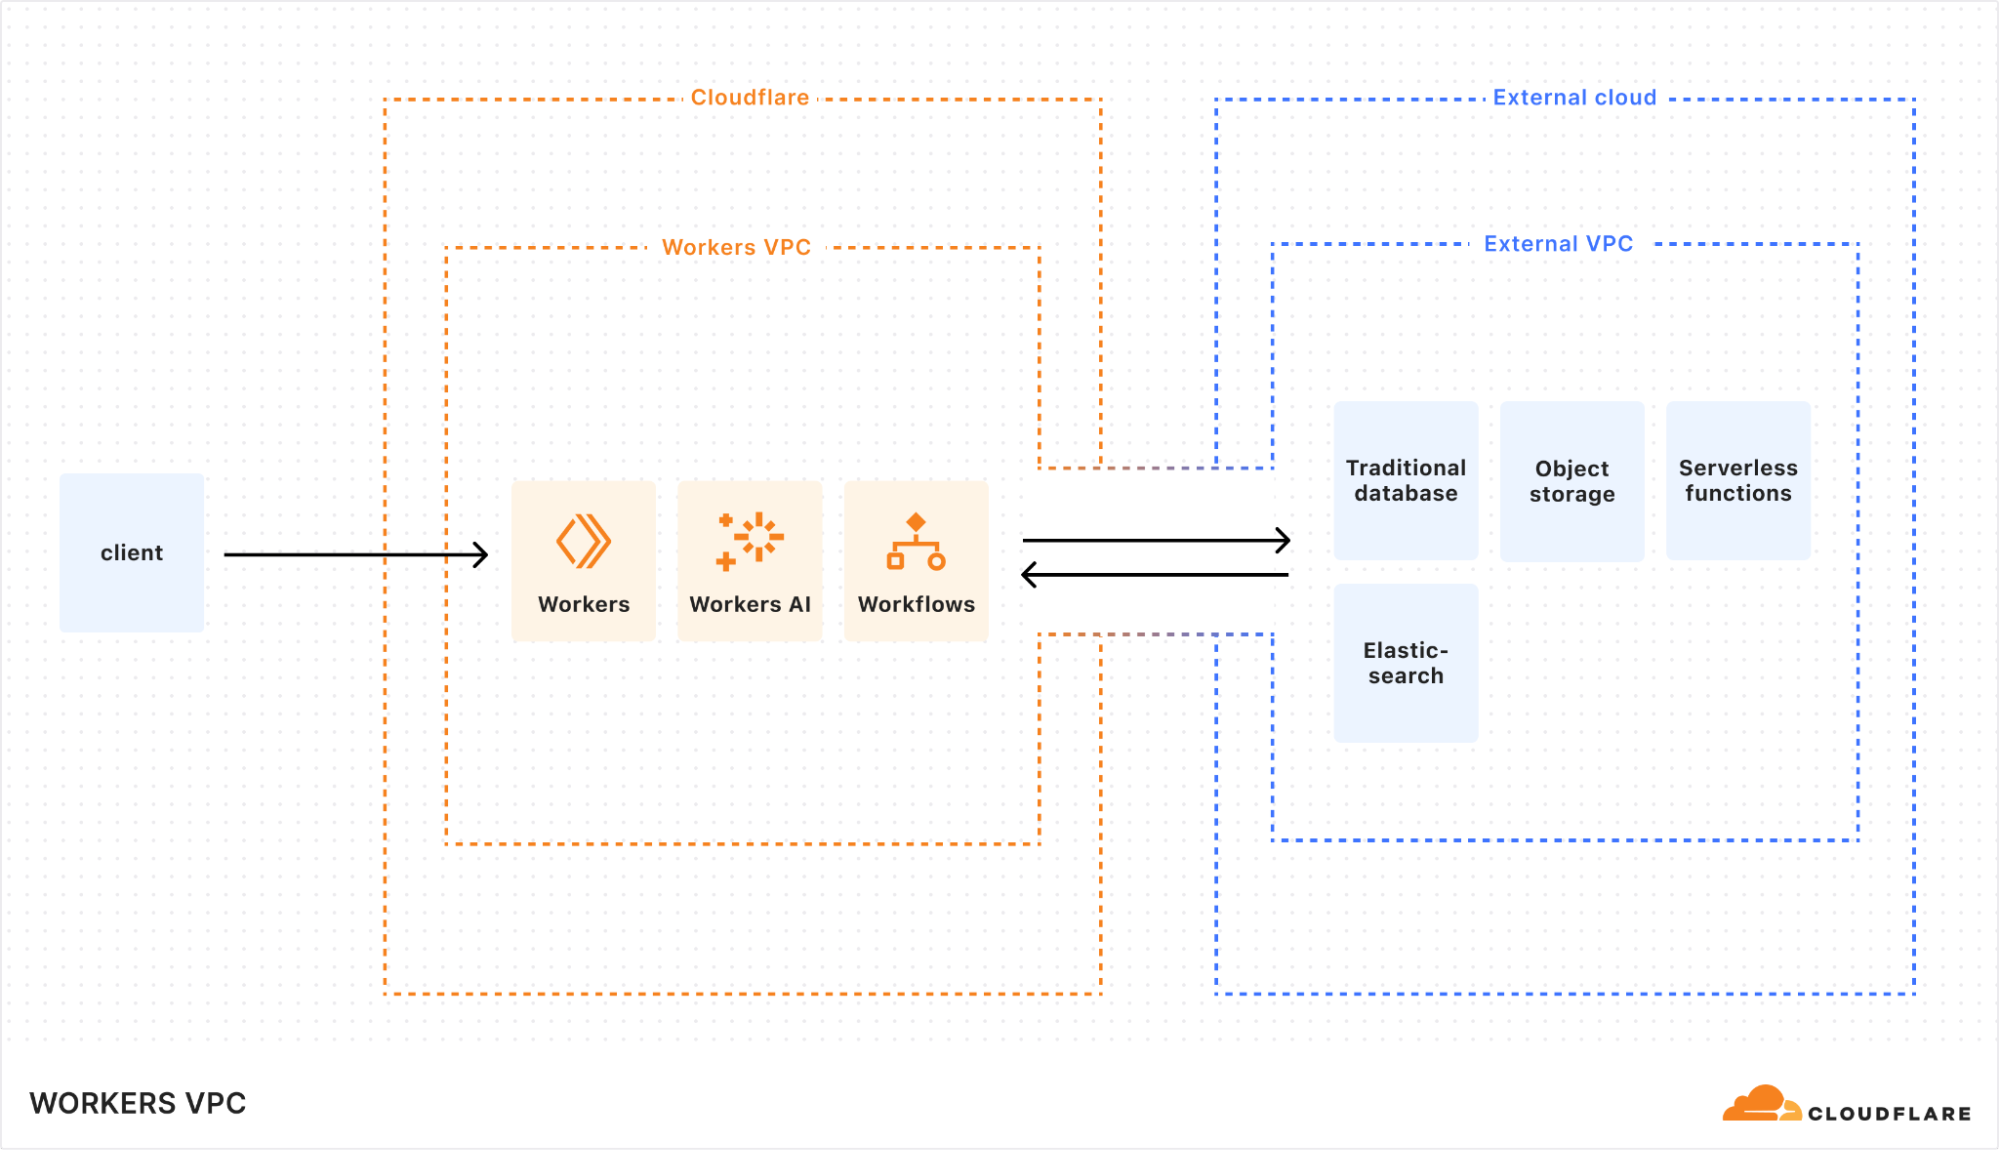
Finally, let’s use an AI agents example — it’s Developer Week 2025 after all! This AI agent is built on Workers, and uses retrieval augmented generation (RAG) to improve the results of its generated text while minimizing the context window.
You’re using PostgreSQL and Elasticsearch in your external cloud because that’s where your data currently resides and you’re a fan of pgvector. You’ve decided to use Workers because you want to get to market quickly, and now you need to access your database. Your database is, once again, placed in a private network and is inaccessible from the public Internet.
While you could provision a new Hyperdrive and Cloudflare Tunnel in a container, since your Workers VPC is already set up and linked, you can access the database directly using either Workers or Hyperdrive.
And what if new documents get added to your object storage in your external cloud? You might want to kick off a workflow to process the new document, chunk it, get embeddings for it, and update the state of your application in consequence, all while providing real-time updates to your end users about the status of the workflow?
Well, in that case, you can use Workflows, triggered by a serverless function in the external cloud. The Workflow will then fetch the new document in object storage, process it as needed, use your preferred embedding provider (whether Workers AI or another provider) in order to process and update the vector stores in Postgres, and then update the state of your application.
These are just some of the workloads that we know will benefit from Workers VPC on day 1. We’re excited to see what you build and are looking forward to working with you to make global VPCs real.
A new era for virtual private clouds
We’re incredibly excited for you to be able to build more on Workers with Workers VPC. We believe that private access to your APIs and databases in your private networks will redefine what you can build on Workers. Workers VPCs unlock access to your private resources to let your ship faster, more performant apps on Workers. And we’re obviously going to ensure that Containers integrate natively with Workers VPC.
We’re actively building Workers VPC on the networking primitives and on-ramps we’ve been using to connect customer networks at scale, and our goal is to ship an early preview later in 2025.
We’re planning to tackle connectivity from Workers to external clouds first, enabling you to modernize more apps that need access to private APIs and databases with Workers, before expanding to support full-directional traffic flows and multiple Workers VPC networks. If you want to shape the vision of Workers VPC and have workloads trapped in a legacy cloud, express interest here.
During Cloudflare’s Birthday Week in September 2024, we introduced a revamped Startup Program designed to make it easier for startups to adopt Cloudflare through a new credits system. This update focused on better aligning the program with how startups and developers actually consume Cloudflare, by providing them with clearer insight into their projected usage, especially as they approach graduation from the program.
Today, we’re excited to announce an expansion to that program: new credit tiers that better match startups at every stage of their journey. But before we dive into what’s new, let’s take a quick look at what the Startup Program is and why it exists.
A refresher: what is the Startup Program?
Cloudflare for Startups provides credits to help early-stage companies build the next big idea on our platform. Startups accepted into the program receive credits valid for one year or until they’re fully used, whichever comes first.
Beyond credits, the program includes access to up to three domains with enterprise-level services, giving startups the same advanced tools we provide to large companies to protect and accelerate their most critical applications.
We know that building a startup is expensive, and Cloudflare is uniquely positioned to support the full-stack needs of modern applications. Our goal is simple: ensure that you have access to the best of Cloudflare’s global network, without the barriers of cost or availability.
Since launching the revamped credits system in September, we’ve learned a lot from the startups in our program, including what they’re building, what they need, and where they need more flexibility. One of the most common requests was more credit tier options.
That’s why we’re introducing new tiers that provide even more options to startups as they scale.
Introducing additional credit tiers
The Cloudflare for Startups Program now offers four credit tiers:
Credit Amount
$5,000
$25,000
$100,000
$250,000
Stage
Bootstrapped, stealth startups
Up-and-coming startups
Seed-funded startups
Tier 1 startups
Description
For startups who are just getting started. This tier is great for building, testing, and iterating your product.
For startups with early adopters and proving product market fit.
For startups that have raised capital, and are experiencing high growth.
For scaling startups that belong to our Tier 1 VC and accelerator network, are building a mission-critical AI application, or are participating in our Workers Launchpad Program.
Criteria
Building a software-based product or service
Founded in the last 5 years
Valid and matching email address
$5,000 criteria plus:
Active LinkedIn
Funded up to $1M
$25,000 criteria plus:
Funded between $1M and $5M
Belong to any of our 250+ approved VC or Accelerator partners
$100,000 criteria plus:
High growth / AI companies, OR
Tier 1 VC & Accelerators
These tiers are designed to offer simplicity and clarity by aligning with where you are in your growth journey. (You can check out eligibility criteria and apply to the Startup Program here). These tiers are still subject to the same Cloudflare for Startups Terms of Service. Credits are valid for up to one year or when all credits are consumed (whichever comes first).
Why are we adding additional credit tiers?
We understand that each startup may have different needs depending on where they’re at in their journey. Some are just getting off the ground, others are scaling rapidly, and each has unique infrastructure needs. With this expansion, we’re reaffirming Cloudflare’s commitment to startups of all sizes, making it easier for you to access the right level of support and resources, exactly when you need them.
Whether you’re launching your MVP or preparing for your next funding round, Cloudflare is here to help you grow.
What can I use the credit tiers for?
The vast majority of Cloudflare products (including all products found on the pay-as-you-go plans) can be used on the Startup Program. Beyond going to the website to see what products are included, below are a few examples of what you can use your credits for:
Build AI applications
Store your training data in R2, build AI-powered agents (via Agents SDK) that autonomously perform tasks with Durable Objects and Workers, or use one of over 50 models to run inference tasks on Cloudflare’s global network.
Create immersive realtime experiences
Deliver live audio and video via our Realtime Kit, enhance the experience with an AI-powered chatbot running on Workers AI to transcribe the call, broadcast to large audiences with Stream.
Build durable multi-step applications
Design and run long-lived, multi-step processes like onboarding flows, document processing, or order fulfillment. Use Workflows to coordinate logic across Workers, Durable Objects, Queues, and AI tasks. Easily handle retries, timeouts, and state management without complex orchestration infrastructure.
What are startups saying about Cloudflare?
Webstudio’s no-code platform is powered by Cloudflare’s Developer Platform
“From a modern design tool, you’d expect real-time collaborative features and would like to have resources as close to users as possible. Since betting on the Developer Platform architecture, Cloudflare has done more for us than any other vendor out there!” – Oleg Isonen (Founder & CEO)
GrackerAI’s cybersecurity research engine runs on Cloudflare’s AI and serverless architecture
“Cloudflare’s fusion of edge computing and AI empowers developers to deploy and utilize AI models with unprecedented efficiency and scale, marking a significant leap forward in how we build and interact with intelligent systems.” – Deepak Gupta (Co-founder & CEO)
Render Better powers faster ecommerce experiences with Cloudflare Workers
“Each month Render Better optimizes billions of monthly requests for ecommerce visitors, delivering faster loading sites that make top brands millions more in revenue. We’re able to scale up with Cloudflare’s serverless workers, handling every request at the network edge within milliseconds, thanks to the rock solid, DX-friendly scope of the Developer Platform.” – James Koshigoe (Co-founder & CEO)
What will you build on Cloudflare?
We can’t wait to see what you will build on Cloudflare. Apply here to take advantage of the Cloudflare for Startups Program.
Cloudflare plays a significant role in supporting the Internet’s infrastructure. As a reverse proxy by approximately 20% of all websites, we sit directly in the request path between users and the origin, helping to improve performance, security, and reliability at scale. Beyond that, our global network powers services like delivery, Workers, and R2 — making Cloudflare not just a passive intermediary, but an active platform for delivering and hosting content across the Internet.
Since Cloudflare’s launch in 2010, we have collaborated with the National Center for Missing and Exploited Children (NCMEC), a US-based clearinghouse for reporting child sexual abuse material (CSAM), and are committed to doing what we can to support identification and removal of CSAM content.
Members of the public, customers, and trusted organizations can submit reports of abuse observed on Cloudflare’s network. A minority of these reports relate to CSAM, which are triaged with the highest priority by Cloudflare’s Trust & Safety team. We will also forward details of the report, along with relevant files (where applicable) and supplemental information to NCMEC.
The process to generate and submit reports to NCMEC involves multiple steps, dependencies, and error handling, which quickly became complex under our original queue-based architecture. In this blog post, we discuss how Cloudflare Workflows helped streamline this process and simplify the code behind it.
Life before Cloudflare Workflows
When we designed our latest NCMEC reporting system in early 2024, Cloudflare Workflows did not exist yet. We used the Workers platform Queues as a solution for managing asynchronous tasks, and structured our system around them.
Our goal was to ensure reliability, fault tolerance, and automatic retries. However, without an orchestrator, we had to manually handle state, retries, and inter-queue messaging. While Queues worked, we needed something more explicit to help debug and observe the more complex asynchronous workflows we were building on top of the messaging system that Queues gave us.
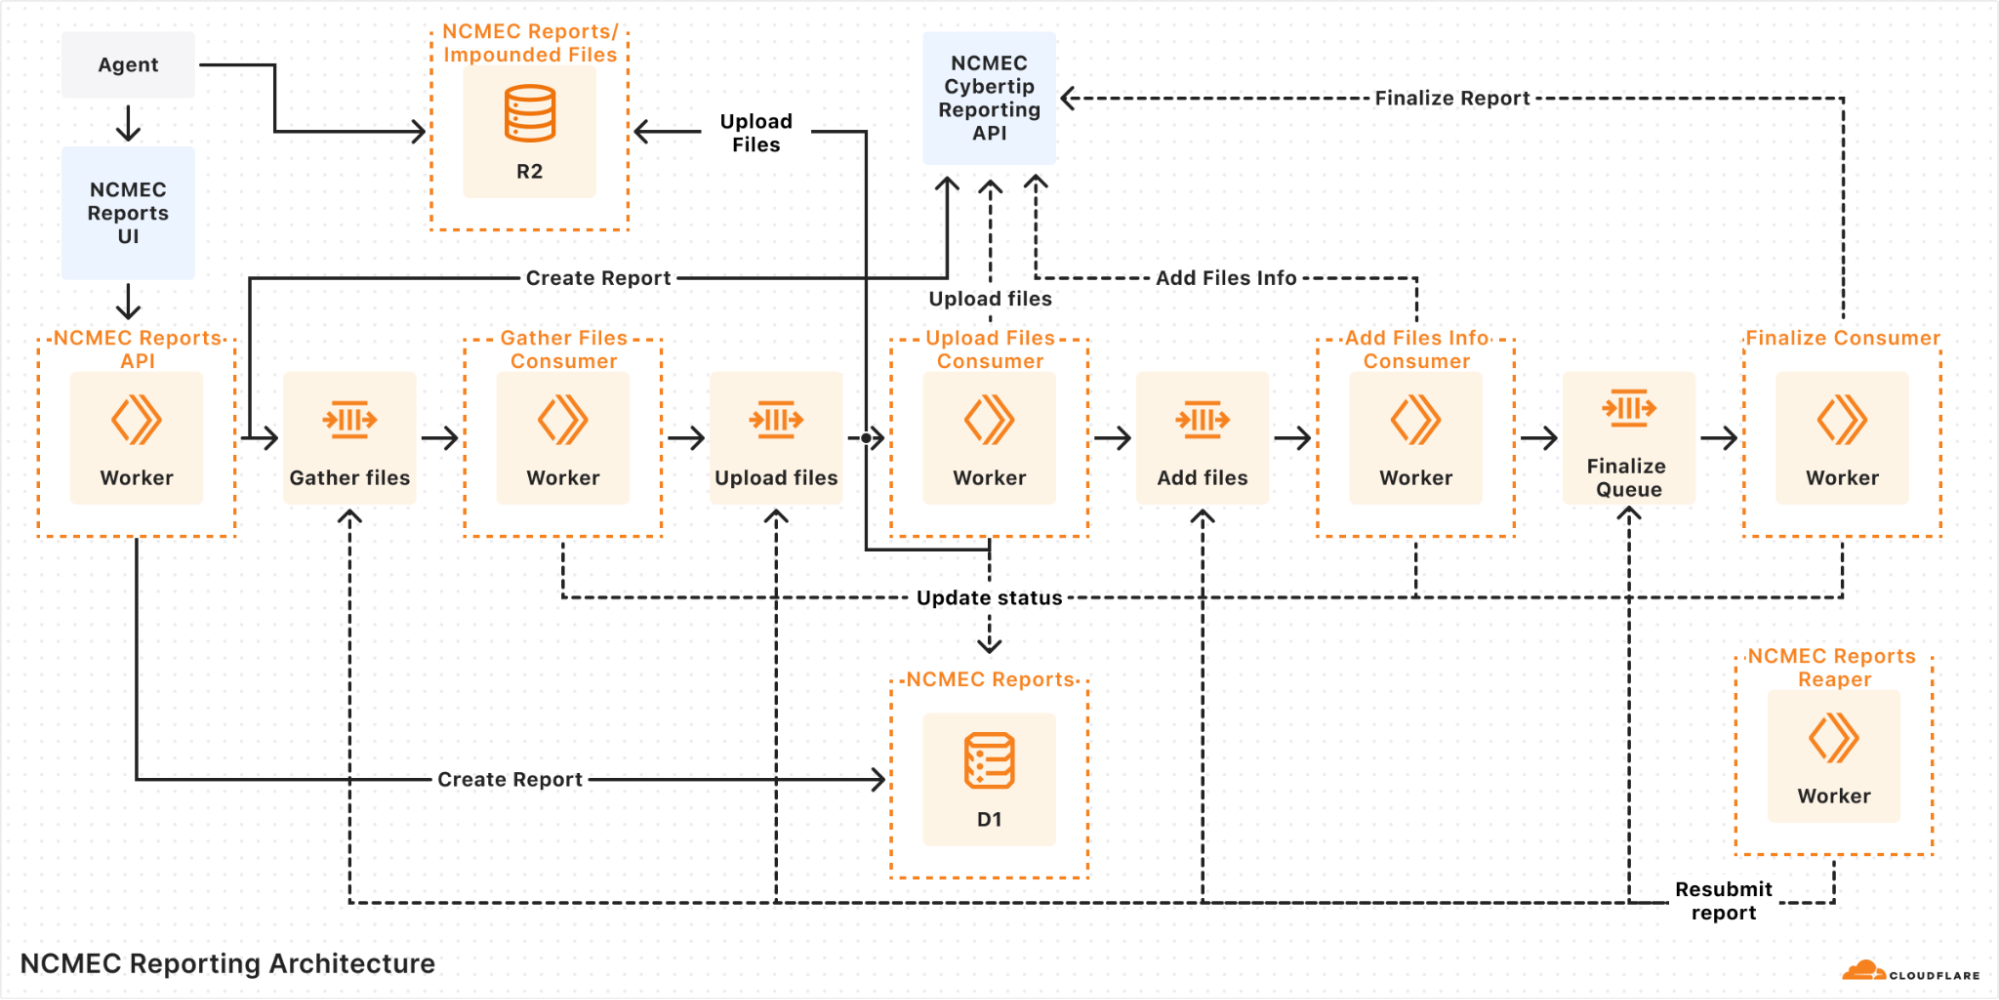
In our queue-based architecture each report would go through multiple steps:
Validate input: Ensure the report has all necessary details.
Initiate report: Call the NCMEC API to create a report.
Fetch impounded files (if applicable): Retrieve files stored in R2.
Upload files: Send files to NCMEC via API.
Finalize report: Mark the report as completed.
A diagram of our queue-based architecture
Each of these steps was handled by a separate queue, and if an error occurred, the system would retry the message several times before marking the report as failed. But errors weren’t always straightforward — for instance, if an external API call consistently failed due to bad input or returned an unexpected response shape, retries wouldn’t help. In those cases, the report could get stuck in an intermediate state, and we’d often have to manually dig through logs across different queues to figure out what went wrong.
Even more frustrating, when handling failed reports, we relied on a “Reaper” — a cron job that ran every hour to resubmit failed reports. Since a report could fail at any step, the Reaper had to deduce which queue failed and send a message to begin reprocessing. This meant:
Debugging was a nightmare: Tracing the journey of a single report meant jumping between logs for multiple queues.
Retries were unreliable: Some queues had retry logic, while others relied on the Reaper, leading to inconsistencies.
State management was painful: We had no clear way to track whether a report was halfway through the pipeline or completely lost, except by looking through the logs.
Operational overhead was high: Developers frequently had to manually inspect failed reports and resubmit them.
Queues gave us a solid foundation for moving messages around, but it wasn’t meant to handle orchestration. What we’d really done was build a bunch of loosely connected steps on top of a message bus and hoped it would all hold together. It worked, for the most part, but it was clunky, hard to reason about, and easy to break. Just understanding how a single report moved through the system meant tracing messages across multiple queues and digging through logs.
We knew we needed something better: a way to define workflows explicitly, with clear visibility into where things were and what had failed. But back then, we didn’t have a good way to do that without bringing in heavyweight tools or writing a bunch of glue code ourselves. When Cloudflare Workflows came along, it felt like the missing piece, finally giving us a simple, reliable way to orchestrate everything without duct tape.
The solution: Cloudflare Workflows
Once Cloudflare Workflows was announced, we saw an immediate opportunity to replace our queue-based architecture with a more structured, observable, and retryable system. Instead of relying on a web of multiple queues passing messages to each other, we now have a single workflow that orchestrates the entire process from start to finish. Critically, if any step failed, the Workflow could pick back up from where it left off, without having to repeat earlier processing steps, re-parsing files, or duplicating uploads.
With Cloudflare Workflows, each report follows a clear sequence of steps:
Creating the report: The system validates the incoming report and initiates it with NCMEC.
Checking for impounded files: If there are impounded files associated with the report, the workflow proceeds to file collection.
Gathering files: The system retrieves impounded files stored in R2 and prepares them for upload.
Uploading files to NCMEC: Each file is uploaded to NCMEC using their API, ensuring all relevant evidence is submitted.
Adding file metadata: Metadata about the uploaded files (hashes, timestamps, etc.) is attached to the report.
Finalizing the report: Once all files are processed, the report is finalized and marked as complete.
Here’s a simplified version of the orchestrator:
import { WorkflowEntrypoint, WorkflowEvent, WorkflowStep } from 'cloudflare:workers';


export class ReportWorkflow extends WorkflowEntrypoint<Env, ReportType> {
  async run(event: WorkflowEvent<ReportType>, step: WorkflowStep) {
    const reportToCreate: ReportType = event.payload;
    let reportId: number | undefined;


    try {
      await step.do('Create Report', async () => {
        const createdReport = await createReportStep(reportToCreate, this.env);
        reportId = createdReport?.id;
      });


      if (reportToCreate.hasImpoundedFiles) {
        await step.do('Gather Files', async () => {
          if (!reportId) throw new Error('Report ID is undefined.');
          await gatherFilesStep(reportId, this.env);
        });


        await step.do('Upload Files', async () => {
          if (!reportId) throw new Error('Report ID is undefined.');
          await uploadFilesStep(reportId, this.env);
        });


        await step.do('Add File Metadata', async () => {
          if (!reportId) throw new Error('Report ID is undefined.');
          await addFilesInfoStep(reportId, this.env);
        });
      }


      await step.do('Finalize Report', async () => {
        if (!reportId) throw new Error('Report ID is undefined.');
        await finalizeReportStep(reportId, this.env);
      });
    } catch (error) {
      console.error(error);
      throw error;
    }
  }
}
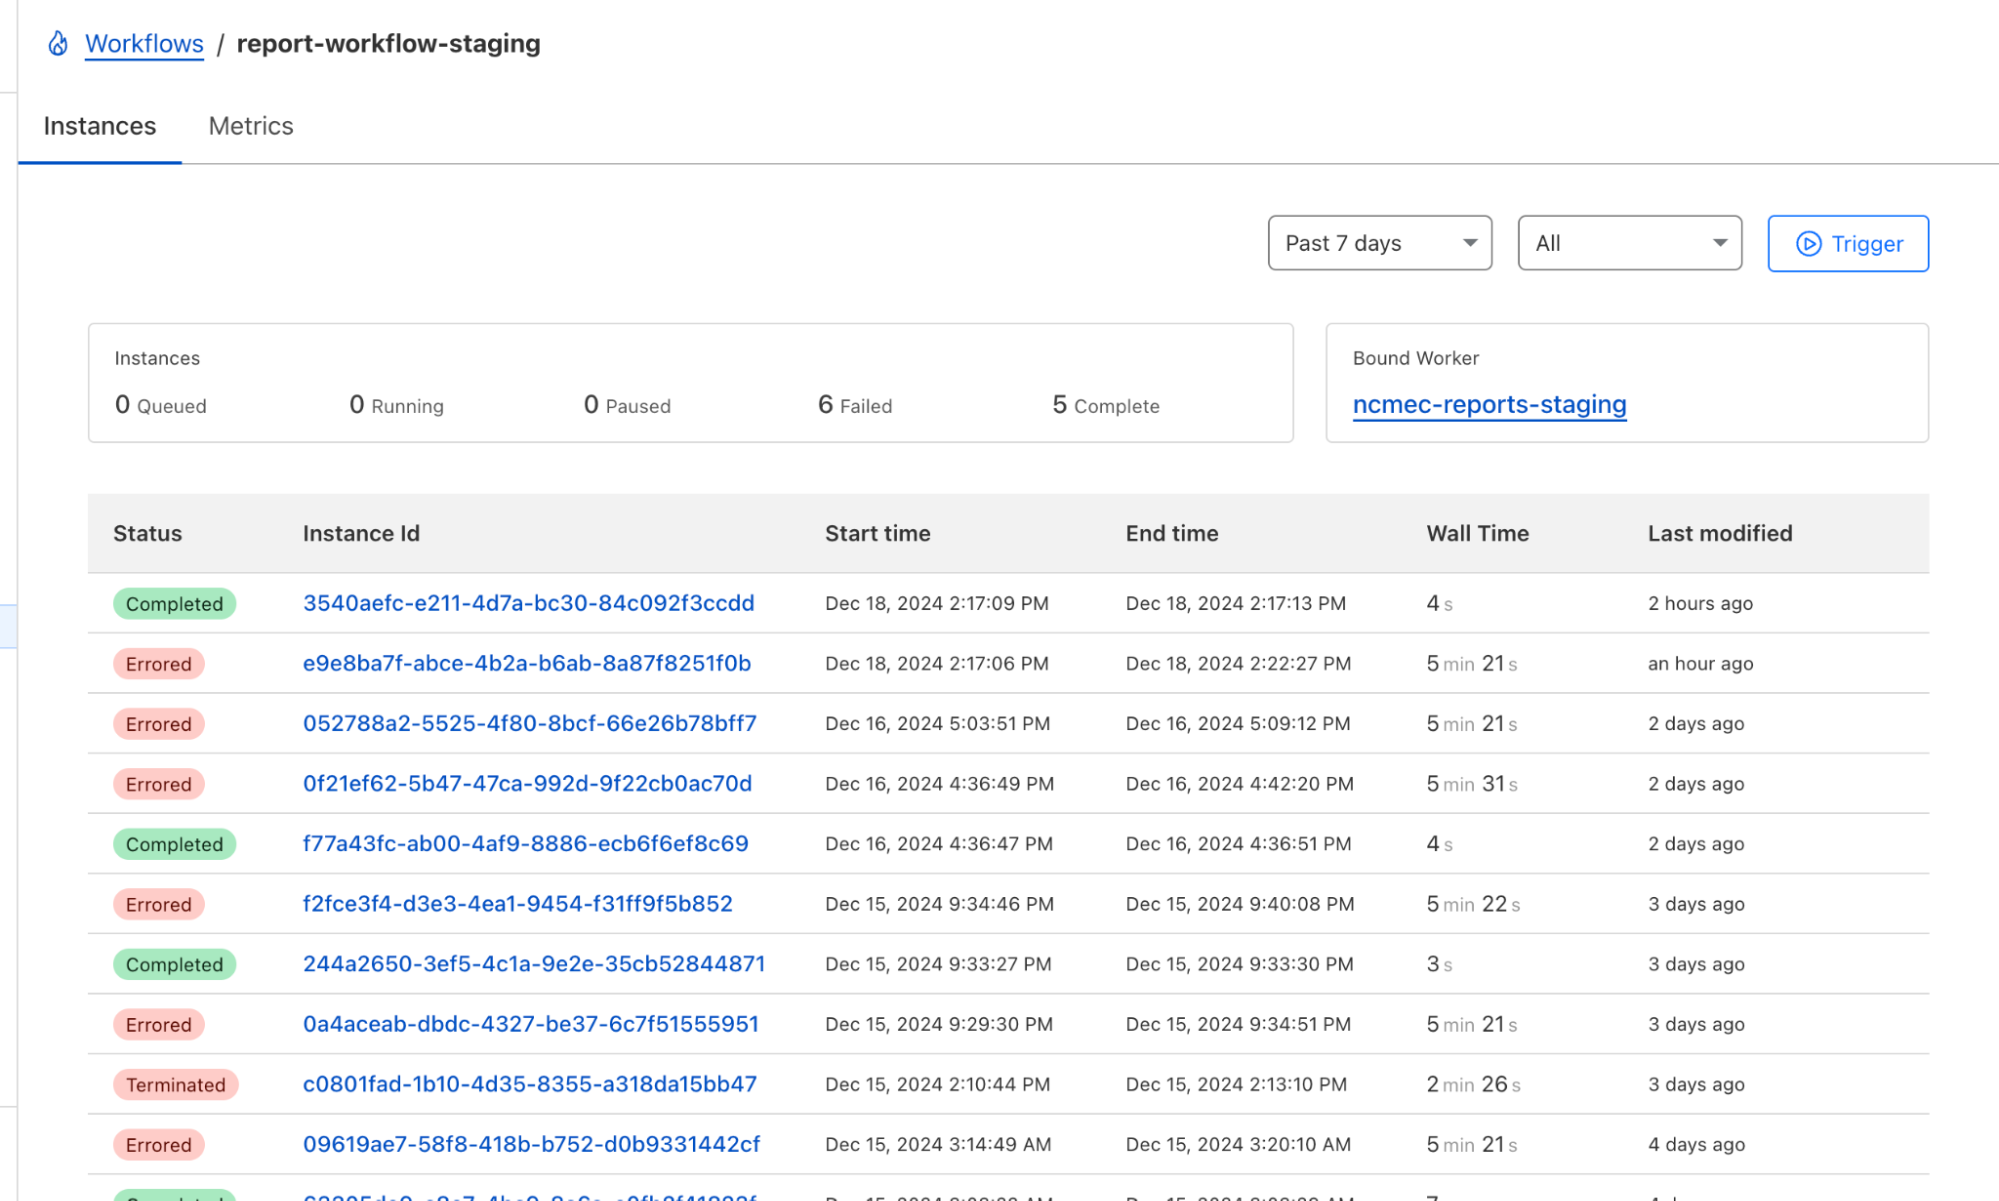
Not only can tasks be broken into discrete steps, but the Workflows dashboard gives us real-time visibility into each report processed and the status of each step in the workflow!
This allows us to easily see active and completed workflows, identify which steps failed and where, and retry failed steps or terminate workflows. These features revolutionize how we troubleshoot issues, providing us with a tool to deep dive into any issues that arise and retry steps with a click of a button.
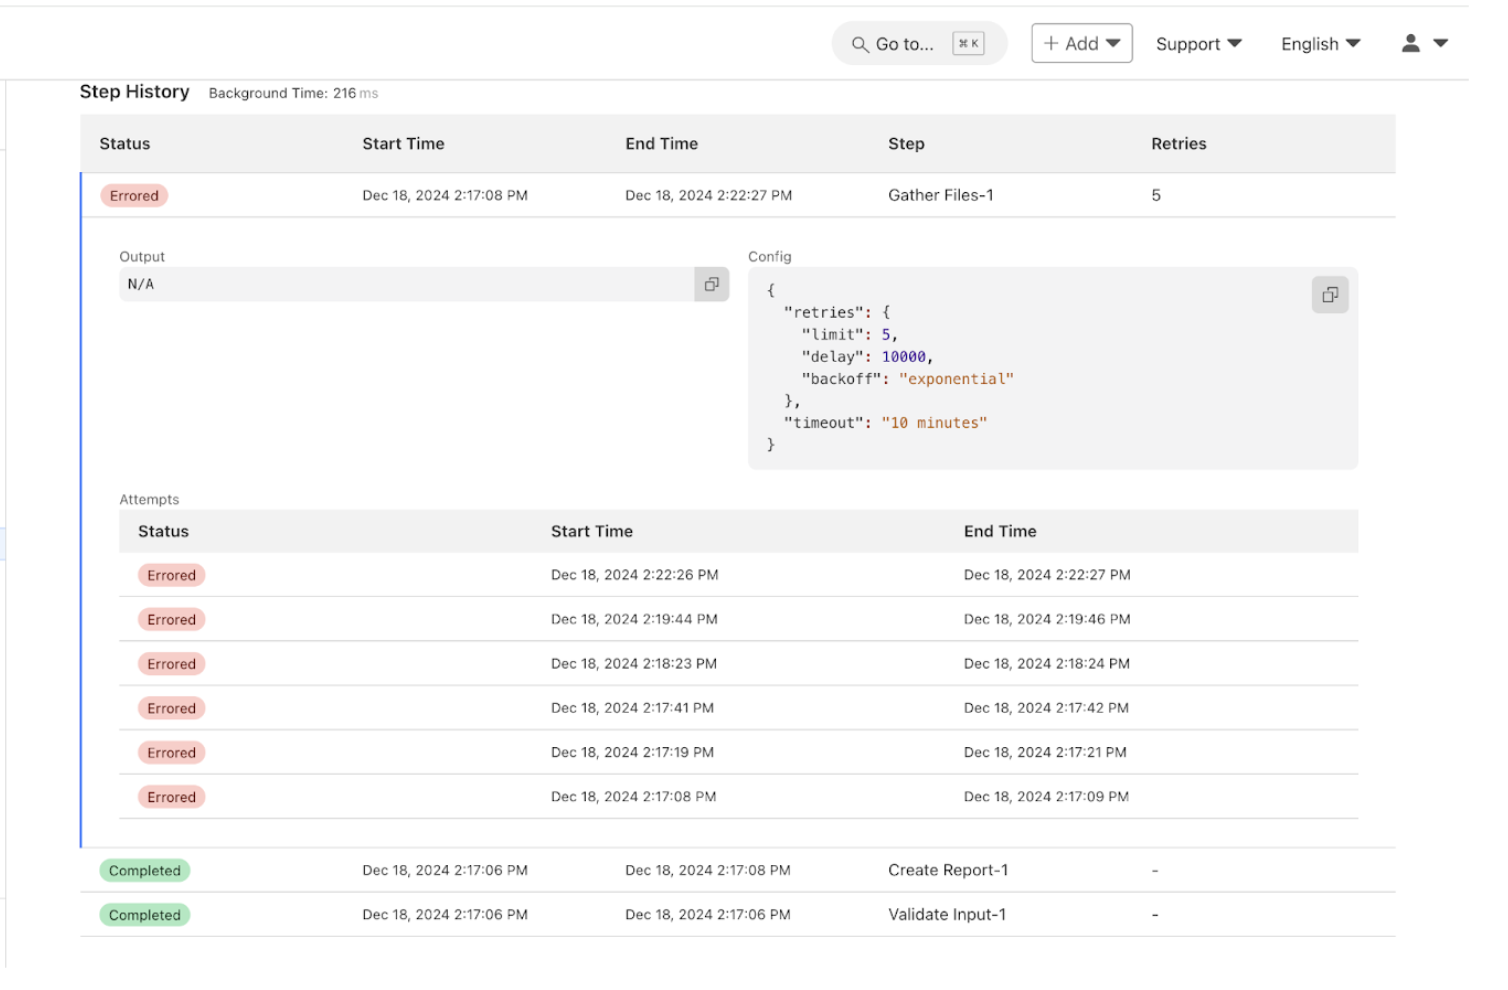
Below are two dashboard screenshots, one of our running workflows and the second of an inspection of the success and failures of each step in the workflow. Some workflows look slower or “stuck” — that’s because failed steps are retried with exponential backoff. This helps smooth over transient issues like flaky APIs without manual intervention.
Cloudflare Workflows Dashboard for our NCMEC Workflow
Cloudflare Workflows Dashboard containing a breakout of the NCMEC Workflow Steps
Cloudflare Workflows transformed how we handle NCMEC incident reports. What was once a complex, queue-based architecture is now a structured, retryable, and observable process. Debugging is easier, error handling is more robust, and monitoring is seamless.
Deploy your own Workflows
If you’re also building larger, multi-step applications, or have an existing Workers application that has started to approach what we ended up with for our incident reporting process, then you can typically wrap that code within a Workflow with minimal changes. Workflows can read from R2, write to KV, query D1 and call other APIs just like any other Worker, but are designed to help orchestrate asynchronous, long-running tasks.
To get started with Workflows, you can head to the Workflows developer documentation and/or pull down the starter project and dive into the code immediately:
Няма българин, който да не е разбрал, че когато държавата е пропита от корупция, това е не само проблем на морала, на репутацията на страната, нито на незаконното забогатяване на държавни чиновници и магистрати, а представлява пряк риск за живота на хората. Смъртта на 12-годишната Сияна на пътя Телиш–Радомирци освети публично най-бруталната машина за убийства – самата държавна система. В състоянието на пътищата – некачествено построени и неподдържани, се оглежда българската корупция. А в органите на реда и правораздавателните институции – нейната безнаказаност.
Когато бащата на Сияна Николай Попов казва, че българската държава е опасна за гражданите си, че убива децата си, това е истината, не просто реакция в състояние на шок. Ако не беше така настойчив, смъртта на единственото му дете щеше да е част от статистиката – тези близо 30 български деца, които губят живота си в катастрофи всяка година.
Според доклад на УНИЦЕФ средно на ден в света загиват около 500 деца на възраст от 0 до 19 години в резултат на пътнотранспортни произшествия, като над 90% от случаите са в държави с ниски и средни доходи.
Медиите и човешкият образ на трагедията
Но този път медиите поставиха трагедията в центъра на новинарските си потоци не само за да попитат как се чувстват опечалените и да отделят по две минути на репортаж от мястото на катастрофата и реакциите. За съжаление, обществото често реагира по-силно и масово само когато една трагедия придобие медийна видимост.
Смъртта на дете (на пътя) никога не е маловажна, но когато бащата на Сияна се появи по новините – със силни думи, емоция и лице, което хората могат да видят, за да му съчувстват, трагедията получи човешки образ. Наред с това Николай Попов посочи с пръст виновните – лошите пътища, отговорна за които е държавата, и липсата на контрол, за което вина носи отново държавната машина.
Гражданският натиск чрез протести, които ще продължат и на 12–13 април под наслов „България няма повече деца за убиване“, доведе до разкритията, че с действията и бездействията си държавните органи изчерпват най-малко един текст от Наказателния кодекс, например чл. 122 за „причиняване на смърт понепредпазливост“. Тоест не са целили смъртта на когото и да е на пътя, но са я причинили в резултат на небрежност, небрежно поведение или неспазване на законови задължения (поддържане на пътищата, контрол и др.). Със сигурност ще се открият и още нарушения, ако следствието и прокуратурата си свършат работата.
Фактите
На пътя Телиш–Радомирци, част от първокласния път I-3, свързващ Ботевград и Плевен, не е правен основен ремонт от 2002 г. За изминалите 23 години само е изкърпван тук-там. От месеци по него е пренасочен и целият транзитен трафик от двата моста на Дунав, тъй като пътят Мездра–Ботевград е затворен за реконструкция.
Политиците започнаха с взаимните обвинения. Настоящият регионален министър Иван Иванов (БСП) хвърля вината върху други преди него, например служебния министър Иван Шишков (2022–2023), който в качеството на експерт обвини огромния поток от тирове. Друг министър на строителството, понастоящем депутат в 51-вото НС – Андрей Цеков (ПП), част от кабинета „Денков“, даде някакво обяснение. Още през 2022 г. Агенция „Пътна инфраструктура“ (АПИ) установява, че участъкът е в „изключително лошо експлоатационно състояние, което не може да бъде поправено чрез превантивно или текущо поддържане, а изисква основен ремонт“.
Обявена е обществена поръчка за технически проект за основния ремонт за 1,063 млн. лв., разплатена е до пролетта на 2024 г., но въпреки това АПИ не е възложила този ремонт. Но пък възлага 35 000 кв.м кръпки. През лятото на 2024 г. Държавната агенция за безопасност на движението по пътищата изпраща доклад на АПИ, че участъкът е с повишена аварийност и висок риск за пътнотранспортни произшествия. Въпреки това първото съобщение на АПИ на 1 април, след като тирът удря насрещно движещия се автомобил, в който пътуват бабата, дядото и Сияна, е, че пътят е в добро експлоатационно състояние, защото се разпространяват „манипулативни твърдения за пътния инцидент“.
Регионалният министър Иван Иванов не иска оставката на председателя на Управителния съвет на АПИ Йордан Вълчев, която пък поискаха от ПП–ДБ (вероятно в опит да се разграничат от Вълчев). Вълчев бе назначен в управата на АПИ със заповед на министър Андрей Цеков, чиято трудова биография е тясно свързана с „Главболгарстрой“. А при служебния кабинет на Димитър Главчев Вълчев оглави АПИ. И сега нагло заявява, че в предходните години не е извършвана нормална пътна поддръжка в участъка, вместо да даде обяснения защо не е разпореден ремонт, а кръпки.
И тъй като няма как да се размине без наказани служители, от АПИ е уволнен шефът на „Поддръжка на пътната инфраструктура“ Даниел Иваничков с прозвище Касичката според бащата на Сияна.
А лидерът на ГЕРБ и Велик-строител-на-пътища Борисов жалее за асфалта.
За 1300 години България никога не се е славила с добри пътища. Само толсистемата може да дисциплинира водачите – и скорост, и товари.
Обещанията
Основният ремонт на пътя Луковит–Плевен ще започне веднага след като се направи проходимост между Ботевград и Мездра и се пусне лот 1 на АМ „Хемус“, обеща регионалният министър. Според него участъкът Ботевград–Мездра ще бъде пуснат за движение в края на юни и трафикът, който сега минава покрай Телиш, ще се върне в „естественото си трасе“. Очаква се цялото трасе Ботевград–Видин да бъде готово до 2029 г.
Първоначално завършването на скоростния път между Мездра и Ботевград бе планирано за 2025 г., но срокът беше удължен до юни 2026 г. Причините за забавянето включват появата на седем свлачища по трасето, за които се изготвят технически решения и укрепителни проекти.
Правителството обяви 37 мерки в опит да намали с 20% жертвите на пътя и срещу всяка една от тях са посочени срок и министър, отговорен за изпълнението ѝ. Кабинетът би могъл да спечели значителен ресурс обществено доверие, ако изпълни и част от тях, например да се ремонтират набелязаните 36 високорискови участъци и камерите на толсистемата да се ползват за установяване на шофьори нарушители. Ако нещо би гарантирало по-дълъг живот на правителството на Росен Желязков, това е успехът във войната по пътищата, не еврозоната.
Сега оборудваме 6 денонощни поста, в които ДАИ, МВР, НАП и горски служители ще дежурят по маршрутите на международните тирове и ще проверяват,
съобщи вицепремиерът и министър на транспорта и съобщенията Гроздан Караджов.
За трикратния премиер Бойко Борисов проблемът е във високата скорост, тоест в неспазването на законите за движение по пътищата. Борисов не споменава некачествената пътна настилка, която не отговаря на стандартите за сцепление, нито пък защо по високорисковите пътища не дежурят повече полицаи, което не би позволило на нарушителите да остават безнаказани, докато не убият някого. Изтритата маркировка и липсващата сигнализация на пътя Телиш–Радомирци бяха сложени след смъртта на Сияна.
Има един въпрос, чийто отговор никога няма да научим:
колко от милиардите, отпуснати за пътища в последните 15 години, още от времето на Бойко Борисов, действително са вложени в пътища, а не в чували.
Ако на чувалите с кеш не се сложи край, чувалите с трупове ще стават все повече.
Security updates have been issued by AlmaLinux (delve and golang and go-toolset:rhel8), Debian (webkit2gtk), Fedora (openvpn, thunderbird, uboot-tools, and zabbix), SUSE (expat, fontforge, govulncheck-vulndb, and kernel), and Ubuntu (haproxy and libsoup2.4, libsoup3).
Any public certification authority (CA) can issue a certificate for any website on the Internet to allow a webserver to authenticate itself to connecting clients. Take a moment to scroll through the list of trusted CAs for your web browser (e.g., Chrome). You may recognize (and even trust) some of the names on that list, but it should make you uncomfortable that any CA on that list could issue a certificate for any website, and your browser would trust it. It’s a castle with 150 doors.
Certificate Transparency (CT) plays a vital role in the Web Public Key Infrastructure (WebPKI), the set of systems, policies, and procedures that help to establish trust on the Internet. CT ensures that all website certificates are publicly visible and auditable, helping to protect website operators from certificate mis-issuance by dishonest CAs, and helping honest CAs to detect key compromise and other failures.
In this post, we’ll discuss the history, evolution, and future of the CT ecosystem. We’ll cover some of the challenges we and others have faced in operating CT logs, and how the new static CT API log design lowers the bar for operators, helping to ensure that this critical infrastructure keeps up with the fast growth and changing landscape of the Internet and WebPKI. We’re excited to open source our Rust implementation of the new log design, built for deployment on Cloudflare’s Developer Platform, and to announce test logs deployed using this infrastructure.
What is Certificate Transparency?
In 2011, the Dutch CA DigiNotar was hacked, allowing attackers to forge a certificate for *.google.com and use it to impersonate Gmail to targeted Iranian users in an attempt to compromise personal information. Google caught this because they used certificate pinning, but that technique doesn’t scale well for the web. This, among other similar attacks, led a team at Google in 2013 to develop Certificate Transparency (CT) as a mechanism to catch mis-issued certificates. CT creates a public audit trail of all certificates issued by public CAs, helping to protect users and website owners by holding CAs accountable for the certificates they issue (even unwittingly, in the event of key compromise or software bugs). CT has been a great success: since 2013, over 17 billion certificates have been logged, and CT was awarded the prestigious Levchin Prize in 2024 for its role as a critical safety mechanism for the Internet.
Let’s take a brief look at the entities involved in the CT ecosystem. Cloudflare itself operates the Nimbus CT logs and the CT monitor powering the Merkle Towndashboard.
Certification Authorities (CAs) are organizations entrusted to issue certificates on behalf of website operators, which in turn can use those certificates to authenticate themselves to connecting clients.
CT-enforcing clients like the Chrome, Safari, and Firefox browsers are web clients that only accept certificates compliant with their CT policies. For example, a policy might require that a certificate includes proof that it has been submitted to at least two independently-operated public CT logs.
Log operators run CT logs, which are public, append-only lists of certificates. CAs and other clients can submit a certificate to a CT log to obtain a “promise” from the CT log that it will incorporate the entry into the append-only log within some grace period. CT logs periodically (every few seconds, typically) update their log state to incorporate batches of new entries, and publish a signed checkpoint that attests to the new state.
Monitors are third parties that continuously crawl CT logs and check that their behavior is correct. For instance, they verify that a log is self-consistent and append-only by ensuring that when new entries are added to the log, no previous entries are deleted or modified. Monitors may also examine logged certificates to help website operators detect mis-issuance.
Challenges in operating a CT log
Despite the success of CT, it is a less than perfect system. Eric Rescorla has an excellent writeup on the many compromises made to make CT deployable on the Internet of 2013. We’ll focus on the operational complexities of running a CT log.
Let’s look at the requirements for running a CT log from Chrome’s CT log policy (which are more or less mirrored by those of Safari and Firefox), and what can go wrong. The requirements center around integrity and availability.
To be considered a trusted auditing source, CT logs necessarily have stringent integrity requirements. Anything the log produces must be correct and self-consistent, meaning that a CT log cannot present two different views of the log to different clients, and must present a consistent history for its entire lifetime. Similarly, when a CT log accepts a certificate and promises to incorporate it by returning a Signed Certificate Timestamp (SCT) to the client, it must eventually incorporate that certificate into its append-only log.
The integrity requirements are unforgiving. A single bit-flip due to a hardware failure or cosmic ray can (andhas) caused logs to produce incorrect results and thus be disqualified by CT programs. Even software updates to running logs can be fatal, as a change that causes a correctness violation cannot simply be rolled back. Perhaps the greatest risk to individual log integrity is failing to incorporate certificates for which they issued SCTs, for example if they fail to commit those pending certificates to durable storage. See Andrew Ayer’s great synopsis for more examples of CT log failures (up to 2021).
A CT log must also meet certain availability requirements to effectively provide its core functionality as a publicly auditable log. Clients must be able to reliably retrieve log data — Chrome’s policy requires a minimum of 99% average uptime over a 90-day rolling period for each API endpoint — and any entries for which an SCT has been issued must be incorporated into the log within the grace period, called the Maximum Merge Delay (MMD), 24 hours in Chrome’s policy.
The design of the current CT log read APIs puts strain on the ability of log operators to meet uptime requirements. The API endpoints are dynamic and not easily cacheable without bespoke caching rules that are aware of the CT API. For instance, the get-entries endpoint allows a client to request arbitrary ranges of entries from a log, and the get-proof-by-hash requires the server to construct inclusion proofs for any certificate requested by the client. To serve these requests, CT log servers need to be backed by databases easily 5-10TB in size capable of serving tens of millions of requests per day. This increases operator complexity and expense, not to mention the high cost of bandwidth of serving these requests.
MMD violations are unfortunately not uncommon. Cloudflare’s own Nimbus logs have experienced prolonged outages in the past, most recently in November 2023 due to complete power loss in the datacenter running the logs. During normal log operation, if the log accepts entries more quickly than it incorporates them, the backlog can grow to exceed the MMD. Log operators can remedy this by rate-limiting or temporarily disabling the write APIs, but this can in turn contribute to violations of the uptime requirements.
The high bar for log operation has limited the organizations operating CT logs to only Cloudflare and five others! Losing one or two logs is enough to compromise the stability of the CT ecosystem. Clearly, a change is needed.
A next-generation CT log design
In May 2024, Let’s Encrypt announcedSunlight, an implementation of a next-generation CT log designed for the modern WebPKI, incorporating a decade of lessons learned from running CT and similar transparency systems. The new CT log design, called the static CT API, is partially based on the Go checksum database, and organizes log data as a series of tiles that are easy to cache and serve. The new design provides efficiency improvements that cut operation costs, help logs to meet availability requirements, and reduce the risk of integrity violations.
The static CT API is split into two parts, the monitoring APIs (so named because CT monitors are the primary clients), and the submission APIs for adding new certificates to the log.
The monitoring APIs replace the dynamic read APIs of RFC 6962, and organize log data into static, cacheable tiles. (See Russ Cox’s blog post for an in-depth explanation of tiled logs.) CT log operators can efficiently serve static tiles from S3-compatible object storage buckets and cache them using CDN infrastructure, without needing dedicated API servers. Clients can then download the necessary tiles to retrieve specific log entries or reconstruct arbitrary proofs.
The static CT API introduces another efficiency by deduplicating intermediate and root “issuer” certificates in a log entry’s certificate chain. The number of publicly-trusted issuer certificates is small (in the low thousands), so instead of storing them repeatedly for each log entry, only the issuer hash is stored. Clients can look up issuer certificates by hash from a separate endpoint.
The submission APIs remain backwards-compatible with RFC 6962, meaning that TLS clients and CAs can submit to them without any changes. However, there is one notable addition: the static CT specification requires logs to hold on to requests as it batches and sequences them, and responds with an SCT only after entries have been incorporated into the log. The specification defines a required SCT extension indicating the entry’s index in the log. At the cost of slightly delayed SCT issuance (on the order of seconds), this change eliminates one of the major pain points of operating a CT log (the Merge Delay).
Having the log index of a certificate available in an SCT enables further efficiencies. SCT auditing refers to the process by which TLS clients or monitors can check if a log has fulfilled its promise to incorporate a certificate for which it has issued an SCT. In the RFC 6962 API, checking if a certificate is present in a log when you don’t already know the index requires using the get-proof-by-hash endpoint to look up the entry by the certificate hash (and the server needs to maintain a mapping from hash to index to efficiently serve these requests). Instead, with the index immediately available in the SCT, clients can directly retrieve the specific log data tile covering that index, even with efficient privacy-preserving techniques.
Since it was announced, the static CT API has taken the CT ecosystem by storm. Aside from Sunlight and our brand new Azul (discussed below), there are at least two other independent implementations, Itko and Trillian Tessera. Several CT monitors (including crt.sh, certspotter, Censys, and our own Merkle Town) have added support for the new log format, and as of April 1, 2025, Chrome has begun accepting submissions for static CT API logs into their CT log program.
A static CT API implementation on Workers
This section discusses how we designed and built our static CT log implementation, Azul (short for azulejos, the colorful Portuguese and Spanish ceramic tiles). For curious readers and prospective CT log operators, we encourage you to follow the instructions in the repo to quickly set up your own static CT log. Questions and feedback in the form of GitHub issues are welcome!
The advent of the static CT API gave us the perfect opportunity to rethink how we run our CT logs. There were a few design decisions we made early on to shape the project.
First and foremost, we wanted to run our CT logs on our distributed global network. Especially after the painful November 2023 control plane outage, there’s been a push to deploy services on our highly available and resilient network instead of running in centralized datacenters.
Second, with Cloudflare’s deeply engrained culture of dogfooding (building Cloudflare on top of Cloudflare), we decided to implement the CT log on top of Cloudflare’s Developer Platform and Workers.
Dogfooding gives us an opportunity to find pain points in our product offerings, and to provide feedback to our development teams to improve the developer experience for everyone. We restricted ourselves to only features and default limits generally available to customers, so that we could have the same experience as an external Cloudflare developer, and would produce an implementation that anyone could deploy.
Another major design decision was to implement the CT log in Rust, a modern systems programming language with static typing and built-in memory safety that is heavily used across Cloudflare, and which already has mature (if sometimes lacking full feature parity) Workers bindings that we have used to build several production services. This also provided us with an opportunity to produce Rust crates porting Go implementations of various C2SP specifications that can be reused across other projects.
For the new logs to be deployable, they needed to be at least as performant as existing CT logs. As a point of reference, the Nimbus2025 log currently handles just over 33 million requests per day (~380/s) across the read APIs, and about 6 million per day (~70/s) across the write APIs.
Implementation
We based Azul heavily on Sunlight, a Go application built for deployment as a standalone server. As such, this section serves as a reference for translating a traditional server to Cloudflare’s serverless platform.
To start, let’s briefly review the Sunlight architecture (described in more detail in the README and original design doc). A Sunlight instance is a single Go process, serving one or multiple CT logs. It is backed by three different storage locations with different properties:
A “lock backend” which stores the current checkpoint for each log. This datastore needs to be strongly consistent, but only stores trivial amounts of data.
A per-log object storage bucket from which to serve tiles, checkpoints, and issuers to CT clients. This datastore needs to be strongly consistent, and to handle multiple terabytes of data.
A per-log deduplication cache, to return SCTs for previously-submitted (pre-)certificates. This datastore is best-effort (as duplicate entries are not fatal to log operation), and stores tens to hundreds of gigabytes of data.
Two major components handle the bulk of the CT log application logic:
A frontend HTTP server handles incoming requests to the submission APIs to add new certificates to the log, validates them, checks the deduplication cache, adds the certificate to a pool of entries to be sequenced, and waits for sequencing to complete before responding to the client.
The sequencer periodically (every 1s, by default) sequences the pool of pending entries, writes new tiles to the object backend, persists the latest checkpoint covering the new log state to the lock and object backends, and signals to waiting requests that the pool has been sequenced.
A static CT API log running on a traditional server using the Sunlight implementation.
Next, let’s look at how we can translate these components into ones suitable for deployment on Workers.
Making it work
Let’s start with the easy choices. The static CT monitoring APIs are designed to serve static, cacheable, compressible assets from object storage. The API should be highly available and have the capacity to serve any number of CT clients. The natural choice is Cloudflare R2, which provides globally consistent storage with capacity for large data volumes, customizability to configure caching and compression, and unbounded read operations.
A static CT API log running on Workers using a preliminary version of the Azul implementation which ran into performance limitations.
The static CT submission APIs are where the real challenge lies. In particular, they allow CT clients to submit certificate chains to be incorporated into the append-only log. We used Workers as the frontend for the CT log application. Workers run in data centers close to the client, scaling on demand to handle request load, making them the ideal place to run the majority of the heavyweight request handling logic, including validating requests, checking the deduplication cache (discussed below), and submitting the entry to be sequenced.
The next question was where and how we’d run the backend to handle the CT log sequencing logic, which needs to be stateful and tightly coordinated. We chose Durable Objects (DOs), a special type of stateful Cloudflare Worker where each instance has persistent storage and a unique name which can be used to route requests to it from anywhere in the world. DOs are designed to scale effortlessly for applications that can be easily broken up into self-contained units that do not need a lot of coordination across units. For example, a chat application can use one DO to control each chat room. In our model, then, each CT log is controlled by a single DO. This architecture allows us to easily run multiple CT logs within a single Workers application, but as we’ll see, the limitations of individual single-threaded DOs can easily become a bottleneck. More on this later.
With the CT log backend as a Durable Object, several other components fell into place: Durable Objects’ strongly-consistent transactional storage neatly fit the requirements for the “lock backend” to persist the log’s latest checkpoint, and we can use an alarm to trigger the log sequencing every second. We can also use location hints to place CT logs in locations geographically close to clients for reduced latency, similar to Google’s Argon and Xenon logs.
The choice of datastore for the deduplication cache proved to be non-obvious. The cache is best-effort, and intended to avoid re-sequencing entries that are already present in the log. The cache key is computed by hashing certain fields of the add-[pre-]chain request, and the cache value consists of the entry’s index in the log and the timestamp at which it was sequenced. At current log submission rates, the deduplication cache could grow in excess of 50 GB for 6 months of log data. In the Sunlight implementation, the deduplication cache is implemented as a local SQLite database, where checks against it are tightly coupled with sequencing, which ensures that duplicates from in-flight requests are correctly accounted for. However, this architecture did not translate well to Cloudflare’s architecture. The data size doesn’t comfortably fit within Durable Object Storage or single-database D1 limits, and it was too slow to directly read and write to remote storage from within the sequencing loop. Ultimately, we split the deduplication cache into two components: a local fixed-size in-memory cache for fast deduplication over short periods of time (on the order of minutes), and the other a long-term deduplication cache built on Cloudflare Workers KV a global, low-latency, eventually-consistent key-value store without storage limitations.
With this architecture, it was relatively straightforward to port the Go code to Rust, and to bring up a functional static CT log up on Workers. We’re done then, right? Not quite. Performance tests showed that the log was only capable of sequencing 20-30 new entries per second, well under the 70 per second target of existing logs. We could work around this by simply running more logs, but that puts strain on other parts of the CT ecosystem — namely on TLS clients and monitors, which need to keep state for each log. Additionally, the alarm used to trigger sequencing would often be delayed by multiple seconds, meaning that the log was failing to produce new tree heads at consistent intervals. Time to go back to the drawing board.
Making it fast
In the design thus far, we’re asking a single-threaded Durable Object instance to do a lot of multi-tasking. The DO processes incoming requests from the Frontend Worker to add entries to the sequencing pool, and must periodically sequence the pool and write state to the various storage backends. A log handling 100 requests per second needs to switch between 101 running tasks (the extra one for the sequencing), plus any async tasks like writing to remote storage — usually 10+ writes to object storage and one write to the long-term deduplication cache per sequenced entry. No wonder the sequencing task was getting delayed!
A static CT API log running on Workers using the Azul implementation with batching to improve performance.
We were able to work around these issues by adding an additional layer of DOs between the Frontend Worker and the Sequencer, which we call Batchers. The Frontend Worker uses consistent hashing on the cache key to determine which of several Batchers to submit the entry to, and the Batcher helps to reduce the number of requests to the Sequencer by buffering requests and sending them together in batches. When the batch is sequenced, the Batcher distributes the responses back to the Frontend Workers that submitted the request. The Batcher also handles writing updates to the deduplication cache, further freeing up resources for the Sequencer.
By limiting the scope of the critical block of code that needed to be run synchronously in a single DO, and leaning on the strengths of DOs by scaling horizontally where the workload allows it, we were able to drastically improve application performance. With this new architecture, the CT log application can handle upwards of 500 requests per second to the submission APIs to add new log entries, while maintaining a consistent sequencing tempo to keep per-request latency low (typically 1-2 seconds).
Developing a Workers application in Rust
One of the reasons I was excited to work on this project is that it gave me an opportunity to implement a Workers application in Rust, which I’d never done from scratch before. Not everything was smooth, but overall I would recommend the experience.
To be clear, these rough edges are expected! The Workers platform is continuously gaining new features, and it’s natural that the Rust bindings would fall behind. As more developers rely on (and contribute to, hint hint) the Rust bindings, the developer experience will continue to improve.
What is next for Certificate Transparency
The WebPKI is constantly evolving and growing, and upcoming changes, in particular shorter certificate lifetimes and larger post-quantum certificates, are going to place significantly more load on the CT ecosystem.
The CA/Browser Forum defines a set of Baseline Requirements for publicly-trusted TLS server certificates. As of 2020, the maximum certificate lifetime for publicly-trusted certificates is 398 days. However, there is a ballot measure to reduce that period to as low as 47 days by March 2029. Let’s Encrypt is going even further, and at the end of 2024 announced that they will be offering short-lived certificates with a lifetime of only six days by the end of 2025. Based on some back-of-the-envelope calculations using statistics from Merkle Town, these changes could increase the number of logged entries in the CT ecosystem by 16-20x.
If you’ve been keeping up with this blog, you’ll also know that post-quantum certificates are on the horizon, bringing with them larger signature and public key sizes. Today, a certificate with an P-256 ECDSA public key and issuer signature can be less than 1kB. Dropping in a ML-DSA44 public key and signature brings the same certificate size to 4.6 kB, assuming the SCTs use 96-byte UOVls-pkc signatures. With these choices, post-quantum certificates could require CT logs to store 4x the amount of data per log entry.
The static CT API design helps to ensure that CT logs are much better equipped to handle this increased load, especially if the load is distributed across multiple logs per operator. Our new implementation makes it easy for log operators to run CT logs on top of Cloudflare’s infrastructure, adding more operational diversity and robustness to the CT ecosystem. We welcome feedback on the design and implementation as GitHub issues, and encourage CAs and other interested parties to start submitting to and consuming from our test logs.
Since the launch of Workers AI in September 2023, our mission has been to make inference accessible to everyone.
Over the last few quarters, our Workers AI team has been heads down on improving the quality of our platform, working on various routing improvements, GPU optimizations, and capacity management improvements. Managing a distributed inference platform is not a simple task, but distributed systems are also what we do best. You’ll notice a recurring theme from all these announcements that has always been part of the core Cloudflare ethos — we try to solve problems through clever engineering so that we are able to do more with less.
Today, we’re excited to introduce speculative decoding to bring you faster inference, an asynchronous batch API for large workloads, and expanded LoRA support for more customized responses. Lastly, we’ll be recapping some of our newly added models, updated pricing, and unveiling a new dashboard to round out the usability of the platform.
Speeding up inference by 2-4x with speculative decoding and more
We’re excited to roll out speed improvements to models in our catalog, starting with the Llama 3.3 70b model. These improvements include speculative decoding, prefix caching, an updated inference backend, and more. We’ve previously done a technical deep dive on speculative decoding and how we’re making Workers AI faster, which you can read about here. With these changes, we’ve been able to improve inference times by 2-4x, without any significant change to the quality of answers generated. We’re planning to incorporate these improvements into more models in the future as we release them. Today, we’re starting to roll out these changes so all Workers AI users of @cf/meta/llama-3.3-70b-instruct-fp8-fast will enjoy this automatic speed boost.
What is speculative decoding?
The way LLMs work is by generating text by predicting the next token in a sentence given the previous tokens. Typically, an LLM is able to predict a single future token (n+1) with one forward pass through the model. These forward passes can be computationally expensive, since they need to work through all the parameters of a model to generate one token (e.g., 70 billion parameters for Llama 3.3 70b).
With speculative decoding, we put a small model (known as the draft model) in front of the original model that helps predict n+x future tokens. The draft model generates a subset of candidate tokens, and the original model just has to evaluate and confirm if they should be incorporated into the generation. Evaluating tokens is less computationally expensive, as the model can evaluate multiple tokens concurrently in a forward pass. As such, inference times can be sped up by 2-4x — meaning that users can get responses much faster.
What makes speculative decoding particularly efficient is that it’s able to use unused GPU compute left behind due to the GPU memory bottleneck LLMs create. Speculative decoding takes advantage of the unused compute by squeezing in a draft model to generate tokens faster. This means we’re able to improve the utilization of our GPUs by using them to their full extent without having parts of the GPU sit idle.
What is prefix caching?
With LLMs, there are usually two stages of generation – the first is known as “pre-fill”, which processes the user’s input tokens such as the prompt and context. Prefix caching is aimed at reducing the pre-fill time of a request. As an example, if you were asking a model to generate code based on a given file, you might insert the whole file into the context window of a request. Then, if you want to make a second request to generate the next line of code, you might send us the whole file again in the second request. Prefix caching allows us to cache the pre-fill tokens so we don’t have to process the context twice. With the same example, we would only do the pre-fill stage once for both requests, rather than doing it per request. This method is especially useful for requests that reuse the same context, such as Retrieval Augmented Generation (RAG), code generation, chatbots with memory, and more. Skipping the pre-fill stage for similar requests means faster responses for our users and more efficient usage of resources.
How did you validate that quality is preserved through these optimizations?
Since this is an in-place update to an existing model, we were particularly cautious in ensuring that we would not break any existing applications with this update. We did extensive A/B testing through a blind arena with internal employees to validate the model quality, and we asked internal and external customers to test the new version of the model to ensure that response formats were compatible and model quality was acceptable. Our testing concluded that the model performed up to standards, with people being extremely excited about the speed of the model. Most LLMs are not perfectly deterministic even with the same set of inputs, but if you do notice something off, please let us know through Discord or X.
Asynchronous batch API
Next up, we’re announcing an asynchronous (async) batch API which is helpful for users of large workloads. This feature allows customers to receive their inference responses asynchronously, with the promise that the inference will be completed at a later time rather than immediately erroring out due to capacity.
An example use case of batch workloads is people generating summaries of a large number of documents. You probably don’t need to use those summaries immediately, as you’ll likely use them once the whole document is complete versus one paragraph at a time. For these use cases, we’ve made it super simple for you to start sending us these requests in batches.
Why batch requests?
From talking to our customers, the most common use case we hear about is people creating embeddings or summarizing a large number of documents. Unfortunately, this is also one of the hardest use cases to manage capacity for as a serverless platform.
To illustrate this, imagine that you want to summarize a 70 page PDF. You typically chunk the document and then send an inference request for each chunk. If each chunk is a few paragraphs on a page, that means that we receive around 4 requests per page multiplied by 70 pages, which is about 280 requests. Multiply that by tens or hundreds of documents, and multiply that by a handful of concurrent users — this means that we get a sudden massive influx of thousands of requests when users start these large workloads.
The way we originally built Workers AI was to handle incoming requests as quickly as possible, assuming there’s a human on the other side that needed an immediate response. The unique thing about batch workloads is that while they’re not latency sensitive, they do require completeness guarantees — you don’t want to come back the next day to realize none of your inference requests actually executed.
With the async API, you send us a batch of requests, and we promise to fulfill them as fast as possible and return them to you as a batch. This guarantees that your inference request will be fulfilled, rather than immediately (or eventually) erroring out. The async API also benefits users who have real-time use cases, as the model instances won’t be immediately consumed by these batch requests that can wait for a response. Inference times will be faster since there won’t be a bunch of competing requests in a queue waiting to reach the inference servers.
We have select models that support batch inference today, which include:
Users can send a batch request to supported models by passing a flag:
let res = await env.AI.run("@cf/meta/llama-3.3-70b-instruct-batch", {
  "requests": [{
    "prompt": "Explain mechanics of wormholes"
  }, {
    "prompt": "List different plant species found in America"
  }]
}, {
  queueRequest: true
});
Check out our developer docs to learn more about the batch API, or use our template to deploy a worker that implements the batch API.
Today, our batch API can be used by sending us an array of requests, and we’ll return your responses in an array. This is helpful for use cases like summarizing large amounts of data that you know beforehand. This means you can send us a single HTTP request with all of your requests, and receive a single HTTP request back with your responses. You can check on the status of the batch by polling it with the request ID we return when your batch is submitted. For the next iteration of our async API, we plan to allow queue-based inputs and outputs, where you push requests and pull responses from a queue. This will integrate tightly with Event Notifications and Workflows, so you can execute subsequent actions upon receiving a response.
iterated on this and now support 8 models as well as larger ranks of up to 32 and LoRA files up to 500 MB. Models that support LoRA inference now include:
In essence, a Low Rank Adaptation (LoRA) adapter allows people to take a trained adapter file and use it in conjunction with a model to alter the response of a model. We did a deep dive on LoRAs in our Birthday Week blog post, which goes into further technical detail. LoRA adapters are great alternatives to fine-tuning a model, as it isn’t as expensive to train and adapters are much smaller and more portable. They are also effective enough to tweak the output of a model to fit a certain style of response.
How do I get started?
To get started, you first need to train your own LoRA adapter or find a public one on HuggingFace. Then, you’ll upload the adapter_model.safetensors and adapter_config.json to your account with the documented wrangler commands or through the REST API. LoRA files are private and scoped to your own account. After that, you can start running fine-tuned inference — check out our LoRA developer docs to get started.
const response = await env.AI.run(
  "@cf/qwen/qwen2.5-coder-32b-instruct", //the model supporting LoRAs
  {
      messages: [{"role": "user", "content": "Hello world"}],
      raw: true, //skip applying the default chat template
      lora: "00000000-0000-0000-0000-000000000", //the finetune id OR finetune name
  }
);
Quality of life improvements: updated pricing and a new dashboard for Workers AI
While the team has been focused on large engineering milestones, we’ve also landed some quality of life improvements over the last few months. In case you missed it, we’ve announced an updated pricing model where usage will be shown in units such as tokens, audio seconds, image size/steps, etc. but still billed in neurons in the backend.
Today, we’re unveiling a new dashboard that allows users to see their usage in both units as well as neurons (built on new Workers Observability components!). Model pricing is also available via dashboard and developer docs on the models page. And if you use AI Gateway, Workers AI usage will also be displayed as metrics now.
New models available in Workers AI
Lastly, we’ve steadily been adding new models on Workers AI, with over 10 new models and a few updates on existing models. Pricing is also now listed directly on the model page in the developer docs. To summarize, here are the new models we’ve added on Workers AI, including four new ones we’re releasing today:
@cf/baai/bge-m3: a multi-lingual embeddings model that supports over 100 languages. It can also simultaneously perform dense retrieval, multi-vector retrieval, and sparse retrieval, with the ability to process inputs of different granularities.
@cf/baai/bge-reranker-base: our first reranker model! Rerankers are a type of text classification model that takes a query and context, and outputs a similarity score between the two. When used in RAG systems, you can use a reranker after the initial vector search to find the most relevant documents to return to a user by reranking the outputs.
@cf/openai/whisper-large-v3-turbo: a faster, more accurate speech-to-text model. This model was added earlier but is graduating out of beta with pricing included today.
@cf/myshell-ai/melotts: our first text-to-speech model that allows users to generate an MP3 with voice audio from text input.
@cf/meta/llama-4-scout-17b-16e-instruct: 17 billion parameter MoE model with 16 experts that is natively multimodal. Offers industry-leading performance in text and image understanding.
[NEW] @cf/mistralai/mistral-small-3.1-24b-instruct: a 24B parameter model achieving state-of-the-art capabilities comparable to larger models, with support for vision and tool calling.
[NEW] @cf/google/gemma-3-12b-it: well-suited for a variety of text generation and image understanding tasks, including question answering, summarization and reasoning, with a 128K context window, and multilingual support in over 140 languages.
[NEW] @cf/qwen/qwq-32b: a medium-sized reasoning model, which is capable of achieving competitive performance against state-of-the-art reasoning models, e.g., DeepSeek-R1, o1-mini.
[NEW] @cf/qwen/qwen2.5-coder-32b-instruct: the current state-of-the-art open-source code LLM, with its coding abilities matching those of GPT-4o.
In addition, we are rolling out some in-place updates to existing models in our catalog:
As we release these new models, we’ll be deprecating old models to encourage use of the state-of-the-art models and make room in our catalog. We will send out an email notice on this shortly. Stay up to date with our model releases and deprecation announcements by subscribing to our Developer Docs changelog.
We’re (still) just getting started
Workers AI is one of Cloudflare’s newer products in a nascent industry, but we still operate with very traditional Cloudflare principles – learning how we can do more with less. Our engineering team is focused on solving the difficult problems that come with growing a distributed inference platform at a global scale, and we’re excited to release these new features today that we think will improve the platform as a whole for all our users. With faster inference times, better reliability, more customization possibilities, and better usability, we’re excited to see what you can do with more Workers AI — let us know what you think!
След дълги разговори за непродуктивното изучаване на чужди езици потърсих представители на онези образователни структури, към които се обръщат родителите, когато търсят качествено чуждоезиково обучение. Това са занимални, езикови центрове и частни училища. Разговорът ни с Ирина Мартинова, Мария Караиванова и Смиляна Димитрова логично се разшири и излезе извън темата за ученето на език, но бяхме единодушни – всичко е възможно дори при сегашните не съвсем оптимални условия. Вижте как може да бъде.
Вас ви има до голяма степен защото образователната система не смогва. Ние нямаме достатъчно места в училищата в големите градове, затова имаме огромни класове и учене на смени. Занималните на практика съществуват само за съвсем начален етап. Езиковото обучение е на все по-ниско ниво, изглежда, се обсъжда и намаляване на часовете по чужд език, а от езикова гимназия се излиза с ниво В2, което е абсолютно недостатъчно, като се има предвид, че в университетите в Австрия и Германия например се изисква ниво C1. Защо правите това, което правите? Бизнес ли е?
Смиляна: Образователната сфера в България е последното място, на което се търси икономическа полза, и между другото, в много други държави също няма такава, защото с труда си в образователната система не произвеждаме продукт, носещ финансова печалба, която да се връща към нас. А всъщност за да се развива добре образованието, както и всичко друго, има нужда от финансиране – това трябва да бъде политика на държавата. Докато тя не вижда смисъл качествено да образова гражданите си, няма как образователната система да се самоиздържа, независимо под каква форма.
Според мен съществуват все повече алтернативни и допълнителни форми на образователни структури, защото толкова е изчезнал фокусът защо го има това училище, каква е целта му, какво се прави в него, че оттам нататък всичко по пътя е обезсмислено.
Няма яснота какво и защо правят децата в часовете. Системата и формата на преподаване са създадени преди столетия и през XVII век са били действително иновация, която позволява достъп до образование на много по-широк кръг от населението. От него се възползва и индустриализацията, като тази форма спомага за подготовката на така необходимата тогава работна ръка. Вече живеем в абсолютно различна реалност, а в същото време подготвяме децата за тази нова реалност по онзи стар начин. И са малко хората, които си казват: „Това не върши работа.“
Мария: Нашия езиков център го има също извън въпроса за икономическите ползи, защото такива на практика почти не съществуват. Има ни заради ефективността на методите, които използваме. Остарелите методи все още са ежедневна практика в училищата – например Grammar-Translation Method, който е въведен през XIX век, за да могат да се четат и превеждат текстове на класически езици. В съвременния свят обаче всички виждаме колко бързо се променя всичко, децата вече са различни, дори не са като тези отпреди пет години. Ето защо да ги караш да преписват и да превеждат текстове е съвсем различно от преподаването на умения за комуникация на съответния чужд език.
Стартирахме занималнята, защото искахме да предложим спокойна среда на децата, възможности за изграждане на умения, необходими за живота в XXI век, възможност за подготовка на учебния материал след училище и преди всичко да освободим семействата от задължението да учат с детето вкъщи. А и заради търсенето от страна на родителите, защото всички знаем за училища, в чиито занимални с 35 деца сборна група работи един учител, който няма как да се справи качествено с този брой ученици. Често чуваме и от децата, че при нас е много спокойно, и те не искат да тръгват по обяд за училище.
Ирина Мартинова: Ръководя курсовете и изпитите в Гьоте-институт България. Моят фокус е върху обучението и квалификацията на учителите по съвременните методи и дидактика на преподаване. Освен това имам дългогодишен опит като преподавател по немски език за възрастни и младежи. За мен най-важното в образованието са принципите на активно учене, което има връзка с реалния живот.
Значи, получавате доверие. Никой не е задължил вашите ученици и родителите им, те идват по собствено желание при всяка една от вас.
Ирина: Да, точно така. Наскоро чух от наш ученик: „Ех, да можеше ученето на немски в училище да е толкова интересно! Там е скучно, а тук е готино. Трябва да се замислим за начина, по който преподаваме.
Смиляна: Ние всички, на първо място, осигуряваме среда, в която децата се чувстват добре. Защото тайната на успешното учене е отношението. Тук преди всичко говоря за емоционалната среда, едва след това за физическата, която също не е маловажна. За да се развива едно дете, то най-напред трябва да е в save mode, в безопасна среда. Когато детето се чувства прието, на сигурно място, и са задоволени базовите му потребности, тогава то се отваря да учи и да развива потенциала си.
Много пъти сме си говорили какво трябва да се промени в образователната система, каква е нормативната рамка, която ни пречи. Няма такава.
Когато работиш с други хора, особено с деца, особено в ролята на учител, е много важно ти самият да бъдеш балансиран, стабилен и емоционално интелигентен. Ако не показваш уважение към детето, няма как да изискваш от него уважение. Ако ти не се държиш с него като с личност и не спазваш същите правила, които изискваш от него – не става. Ние възпитаваме чрез поведението си, не само чрез думите си.
Наистина ли е неефективно изучаването на чужд език в повечето български училища?
Мария: Редовно когато децата идват при нас в частната занималня и се стигне до домашното по чужд език, виждаме, че основното е да преписват текст или думи. Един от най-фрапиращите случаи беше, когато второкласничка дойде с 14 нови думи по испански и трябваше всяка дума да бъде написана по 10 пъти, което е 140 думи. Аз карам шестокласниците по време на тестовете за умения за писане да ми напишат между 80 и 100 думи. Това дете във втори клас трябваше да напише 140 думи, плюс да си напише домашното по математика, плюс да си напише домашното по български. Сами можете да си представите едно дете във втори клас каква скорост на писане има, колко време му отнема това домашно и после колко запомня от правописа на тези думи.
Защо писането на думи не помага? Защо вашите ученици например не пишат думи по пет реда?
Мария: Нашите ученици пишат думи, но не ги преписват. Защото преписването на думи по Х на брой пъти прескача цялата фоник система, която е много естествен начин за децата да научат буквите и четенето на английски език. Фотографското запаметяване чрез повторения как се пише всяка дума няма същия ефект и не включва необходимия мисловен процес, ако изобщо включва някакъв. Нашите ученици пишат думи в различни видове контекст, в който сами трябва да изберат коя дума как да използват. Включваме разнообразни игри, като скрабъл, магнитни буквички и други, които извеждат писането извън стандартния формат на листа и химикалката. Постепенно децата откриват, че да се чете и пише на английски е забавно и не е страшно. Имаме първокласници, които вече четат на английски.
Ирина: Езикът се учи в неговата структурна цялост и никога една дума не може да бъде изолирана, защото тя не съществува никъде така, освен в речника. Нито една граматика или пък дума не може да бъде самоцел. Те са само начинът да изразим това, което искаме да кажем. В Гьоте-институт учим чрез конкретни действия – искам да поръчам нещо в ресторанта, значи уча цялата фраза: „Бихте ли ми донесли…“ или „Моля да поръчам…“. Автоматизацията, запомнянето на тези структури допринасят за запомнянето и на думите. Знаете ли колко пъти трябва да бъде срещната една дума, за да бъде запомнена? Преди години се твърдеше, че е 76 пъти. Най-актуалните невродидактически проучвания обаче показват, че думата трябва да бъде употребена 100 пъти, така че тя никога повече да не излезе от главата ти.
Смиляна: Дори в българския език не вадим думата просто така, а по-скоро я включваме в контекста на цялата речева ситуация. Невролозите казват, че за да запомниш нещо, трябва да направиш нови връзки в мозъка си. Не правиш никакви връзки, пишейки механично една дума. Да не говорим за децата, които имат да напишат думата 10 пъти и пишат 10 пъти първата буква, 10 пъти втората и т.н. Виждала съм и два химикала, залепени един за друг, за да пишат наведнъж на два реда. Дори самите деца показват, че това е абсолютно губене на време, и търсят всяка вратичка, за да го заобиколят.
Мария Караиванова: Преподавам английски език и работя с деца от 25 години. Имам и над 15-годишен опит в обучението и изграждането на преподавателски екипи по чужди езици. Преди 13 години основах и ръководя своя чуждоезикова школа – Mary Eton Language Club, в която използваме съвременни методи за учене на чужди езици. В последните няколко години успешно превръщаме ученето на английски език в ефективна възможност за разгръщане на уменията на XXI век у децата.
Често чувам от родители: „Ние едно време, като правихме това в училище – и какво ни е станало?“ Наясно са, че е имало години наред безсмислен труд, например преписването на думи, но факт – какво пък толкова ни е станало на нас и защо да не продължаваме така, както си е било досега…
Ирина: Това ни отне възможността да се научим на критично мислене. А то е много важно.
Ние бяхме научени да преповтаряме, но не и сами да произвеждаме, което дава отражение в цялото ни общество.
Мария: Преписването на думи и на текстове кара децата да чакат нещо наготово да се случи с тях. Те не са проактивни и този процес ги лишава от развиването на всички мисловни умения, на които всеки един от нас би бил способен, а именно критичното мислене, творческото мислене…
Тези умения са вписани във всички нормативни документи като цели на образованието. Погледнете държавните образователни стандарти.
Мария: Как точно се развива критично мислене с преписване? И още повече – съвременните деца са заобиколени от езика. Деца в IV и V клас владеят английски по-добре от изискваното от тях ниво в училище. Защото те имат много по-обширен достъп до езика посредством медии, хобита, музика, филми. Вече говорим за мултимодалност при ученето на чужди езици. Освен четене, писане, слушане и говорене включваме и гледане на видеа, постери, шрифтове, мемета и всичко останало, което носи смисъл в комуникацията.
Децата комуникират свободно, разбират дори мемета, в които е заложен хумор – те го схващат, това е усвояването, живеенето в езика. Основната цел на ученето на който и да било език всъщност е комуникацията. Тя при преписване не съществува. Познавам петокласници, които си говорят и пишат в чатовете на английски. А в училище им дават да преписват думи. После се чудим откъде идва невниманието в час, говоренето, така дискутираната „лоша дисциплина“. Това често избива в междуличностни конфликти с учителя. Който от своя страна трябва да е емоционално стабилен, за да реагира адекватно.
Смиляна: Правя стъпка назад и си припомням любим цитат, че детето всъщност учи това, което прави. Ако аз преписвам думи, се уча да преписвам думи. Ако гледам как някой решава задачи, се уча да гледам как някой решава задачи. Тук въпросът отново е какво целим с определени упражнения или начин на учене. При нас освен часовете, в които децата учат граматика и правопис, имаме часове с нейтив спийкър, в които децата са свободни да разговарят на различни теми. Там не се обръща толкова внимание на правилната граматика, а се учиш да комуникираш, да разбираш. Ето го и повтарянето на думи, но през изживяването. Граматиката също си идва на мястото с практика. Имаме и специален предмет – сценичен английски. В него децата използват езика в съвсем различна ситуация. Не ограничаваме учителите с конкретен учебник. Моята дъщеря вече трета година има веднъж седмично едно и също домашно по английски – есе от определен брой думи на всякакви теми от живота, които са свързани с възрастта ѝ и с нещата, които я вълнуват.
Всичко това е много хубаво, но какво става в голяма група, каквито са повечето класове в училищата?
Ирина: Има как да се работи в много големи групи. Има методика и дидактика, която владее голямата група, но пак стигаме до квалификацията на преподавателите, които трябва да знаят как става, с какви форми, с какви методи и тук апелът към университетите, които подготвят тези кадри, е да се ориентират към модерните практики на преподаване. Които, за съжаление, едва сега си пробиват път и не са основна част от университетското образование. Те могат да бъдат придобити алтернативно, след като вече си учил няколко години филология. След това започваш да учиш как всъщност да преподаваш.
Смиляна: Да не забравяме, че в училищната система има страшно много преподаватели, които са специалисти в областта си, но не знаят как да преподават. И това, че са взели една педагогическа квалификация за един семестър и са минали някаква дидактика набързо, не ги прави в никакъв случай добри преподаватели.
Когато търсим диалог с образователната система, много често насреща ни цитират наредби. Коя е наредбата, която забранява по-адекватни образователни действия? Вие правите ли нещо забранено?
Смиляна: Не съм съгласна, че съществуващите наредби налагат крайни ограничения. Че има безсмислици, че има противоречащи си наредби, е безспорно. Има някои спънки от нормативната уредба, но също така бих казала, че през годините много от ограниченията отпаднаха, например тези за разпределението на учебен материал, промяната на норматива часове от седмична на годишна база и т.н. Тоест ако има желание, има как в настоящата нормативна уредба да се правят нещата по смислен начин. Частните училища са доказателството за това.
Според мен проблемът е другаде. Той е в нас, хората. От една страна, имаме онази част от учителите, които са решили, че това е удобна професия, защото си тръгват уж на обяд, и някои действително така правят – влизат в клас, изпяват си урока и си тръгват. Все едно да си спортист, който не тренира, а само се явява на състезания. От друга страна, имаме родители с различни, често дори противоречащи си изисквания и очаквания и вместо да са партньори в образователния процес, създават конфликт, от който страда най-много собственото им дете. Може би защото са загубили доверие в системата – аз не ги упреквам. Моята роля като педагог е не само да подпомагам и развивам децата, а и да създавам доверена връзка с техните родители. И в това се включва непрекъснато да усъвършенствам себе си. А колко по-удобно е да не правиш нищо различно, криейки се зад ограниченията на системата.
Ирина: Давам ви пример с две преподавателки, които работят в общинско училище в по-малък град. От две години те са част от нашите преподаватели в Зелената диплома, с която може да преподаваш в Гьоте институт в цял свят. Преподавателките придобиха такава квалификация и казват: „Прекрасно е, че посещаваме от две години тези стойностни обучения, но абсурдът е, че вече не сме харесвани от колегите. Ние вече знаем как може да бъде и как не е в училище. Искаме да променим например подредбата на масите и столовете в класната стая, но не ни е позволено от директора. Математичката, която след това ще влезе в същата стая, започва да недоволства – тя не иска да има такива островчета, на които да се работи по групи, иска да преподава фронтално.“ Разбирате ли за колко елементарни неща трябва да се водят битки?
Смиляна Димитрова: По професия съм начален учител и обичам професията си, защото виждам смисъл в нея. За разлика от системата, в която се налага да я практикувам. През последните 25 години преминах като учител през всички форми на образование – държавни и частни училища, школи, занимални, частни групови и индивидуални уроци, неформално образование. От 6 години съм част от ръководството на ЧОУ „Фюжън“, в което основна цел е да подпомагаме цялостното и пълноценно развитие на децата. Заедно с най-прекрасния и вдъхновяващ екип ежедневно работим за създаването на подкрепяща среда, в която децата да разгръщат неограничения си потенциал.
Вие идвате от стандартното средно образование в България и сте негови „продукти“. Какво ви направи различни?
Ирина: Знаеш ли колко пъти съм си мислила точно това? Знам как сме учили немски с таблиците, които трябва да бъдат наизустени – винаги таблици, винаги контролни, червени от горе до долу, които демотивират… При мен беше стечение на обстоятелствата, щастлива развръзка в моя живот, че все пак се занимавам с немски, противно на системата, в която съм и от която съм произлязла. Мотивацията е невидимата сила, която те тегли нагоре. Само когато се чувстваш приет, можеш мотивирано да преследваш своите цели, така че не е редно да си казваме: „Ама и ние просто излязохме от тази система.“
Мария:
Не искам да съм продукт на системата. Искам да мога да предоставя на децата алтернатива на това, от което сме излезли.
Когато ние бяхме ученици, за съжаление, нямаше алтернативи. Но след това, когато започнах да се образовам по педагогика, филология, други методи на преподаване и на учене, съм виждала примери, за които да си кажа: „Ето така трябваше да бъде, така е можело да бъде.“ Искам да бъда алтернативата.
Смиляна: Имах късмет с прекрасна начална учителка. След това имах късмета да съм в специализирана паралелка, в която най-важното беше математиката, а аз я обичам. След това имах късмета родителите ми да ме подкрепят и да отида в алтернативно образование, защото завърших художествено училище, в което нещата стоят доста по-различно от стандартната образователна система. Реших да се занимавам с образование, защото си мислех, че е суперяко, понеже моят път е бил такъв.
Моята баба е мечтала да стане учителка, за да дава на децата и да им помага. На мен учителската професия ми е била показвана от тази страна, от смислената страна.
Когато реших да се занимавам с образование и минах през различните му форми, първо започнах в частна занималня, после в държавно училище, където останах 4 години и от което си тръгнах силно огорчена. Тогава си казах, че ако се върна някога в образователната система, няма да е в никакъв случай в държавния сектор, защото искам да имам по-голяма свобода да направя нещата така, както е необходимо. Продължавах да се лутам, докато не създадохме училище, чиято основа беше да видим какво досега не работи и как би трябвало да работи.
Представете си, че сте насаме с образователната система. Можете да ѝ кажете всичко. Какво ще е то?
Ирина: „Научете децата на критично мислене. Задайте рамката в часа. Провокирайте децата, за да могат да мислят, а не да възпроизвеждат каквото учителят е изпял.“
Мария: Аз бих ѝ казала, че ѝ съчувствам за условията, в които е поставена, и се опитвам да я разбера, но тя също да се опита да бъде малко по-кооперативна и да не застава на нож с родители и с частния сектор.
Смиляна: „Моля те, осъзнай се! Каква ти е целта? Постигаш ли я? Ти можеш повече! Трябват ти само малко желание и смисъл!“
Microsoft discovered eleven vulnerabilities in GRUB2, including integer and buffer overflows in filesystem parsers, command flaws, and a side-channel in cryptographic comparison.
Additionally, 9 buffer overflows in parsing SquashFS, EXT4, CramFS, JFFS2, and symlinks were discovered in U-Boot and Barebox, which require physical access to exploit.
The newly discovered flaws impact devices relying on UEFI Secure Boot, and if the right conditions are met, attackers can bypass security protections to execute arbitrary code on the device.
Nothing major here. These aren’t exploitable out of the box. But that an AI system can do this at all is impressive, and I expect their capabilities to continue to improve.
Може ли някой да се справи с 8 джуджета накуп, къде ще се озове Мъск скоро и кое ще е следващото число, което ще се падне в 5 от 35? Отговорите – само тук, само сега, само за вас!
Следете видеорубриката на Елена Телбис за „Тоест“ и в Instagram и TikTok.
Добрата инвестицията винаги носи в себе си доза риск. Въпросът е той да бъде минимизиран и пресметнат преди да се хвърлим в ново начинание.
В последно време инвестицията в недвижм имот е доста популярна, въпреки че доходността от нея е сравнително ниска.
Повлияни от множеството подкасти и обучения, купувачите гледат на покупката на недвижим имот като на инвестиция, но на практика това е по-скоро спестяване под формата на недвижим имот.
За да гледаме на покупката на имот като на инвестиция, следва да реализираме и определена печалба. Но зад всяка печалба стои и съответното изразходвано време. Много често отдаването под наем на имот се счита за пасивен доход. През последните години обаче това не е точно така. Изобщо схващанията за доходите, бизнеса и парите, които се налагат чрез обучения и тренинги са доста остарели концепции, и не отговарят на съвременните условия. Примерът за пасивния доход от наем е особено подходящ в случая.
Към днешна дата около 62% от сделките с недвижими имоти в София и Пловдив са с ипотечен кредит, който има своите разходи под формата на лихви, такси, застраховки… С две думи изтеглянето на ипотечен кредит и покупката на недвижим имот е всичко друго само не и пасивно занимание. Имате вадене на документи за кредит, имате обикаляне за избор на жилище и може би най-големият ужас за дамите – майсторите, които да направят ремонт и превърнат мястото от апартамент в дом, за който някой би платил разумна цена. Всичко това се заплаща с колосално време и средства. В изключително редки случаи е възможно да се наемат дизайнерки бюра, които пък да намерят майстори и да упражнят адекватен контрол върху тяхната дейност. Обикновенно, ако се използва тази схема координацията и контрола се изпълнява от собственика на апартамента с цел намаляването на разходи.
Веднъж завършен и обзаведен апартаментът продължава да се нуждае от време и средства. Следва адвокат, който да изготви договор за наем и срещи с потенциални наематели. Често брокерите на недвими имоти се опитват да изземат функциите на адвоката и да предложат „стандартен договор“ за наем, но това е защото в поседствие те не носят отговорност, ако наемателите са некоректни. Проблемите с наематели стават все по-чести и почти винаги водят до нова сага с майстори. Затова договорите за наем не бива да бъдат подценявани. Няколко наема като депозит вършат работа за отсяване на потенциални наематели, но не решават проблема с щетите, които обикновено надхвърлят сериозно тези депозити.
Текущият контрол върху използването на имота се оказва най-добрата превантивна мярка за бъдещи проблеми, но това също изисква време и внимание.
В крайна сметка доходността от отдаването под наем на един имот се „върти“ около 3-4% годишно, ако вземем предвид разходите по освежителен ремонт след всеки наемател, разходите по ипотеката, поддръжката, данъците и амортизацията на обзавеждането и уредите. Разбира се винаги има варианти имотът да се дава необзаведен, да се включват в договорите клаузи за ремонт, но това пък се отразява върху наемната цена и сътветно доходността от инвестицията.
От моята практика, най-печаливши от покупката на второ жилище са хората, които гледат на него като на форма на спестявания, което изгражда една по-ралична концепция.
Когато говорим за спестявания това означава достатъчно високи доходи, които не се харчат в рамките на месеца. Никога не е било разумно тези пари да се спестяват в банка, а недвижимите имоти винаги са било доста добра алтернатива за спестяване. Една от причините е, че чисто исторически цената им расте повече от нивото на инфлацията. Имайте предвид, че лихвите по депозитите в банките винаги са по-ниски от инфлацията и затова парите в банка се обезценяват.
Ефекта от спестяване в имот се мултиплицира многократно, когато обвържем срока на кредита (ако ползваме кредит) с възрастта на децата. Тогава нашите наследници получават наистина добър старт в живота, а цената на имота може да им послужи за добър стартов капитал за бизнес, пътуване или образование. Малко хора съобразяват, че спестяването под формата на имот е много по-доходоносно от примерно спестовна застраховка живот. Освен това вложените средства са добре защитени от актив, чиято цена расте с времето и ако поддържаме имота в добро състояние, то той ще бъде ликвиден във всеки един момент. Дори да изпаднем във временна невъзможност да изплащаме ипотеката, опцията с продажбата му винаги е налице, като това най-вероятно ще доведе до реализиране на печалба от разликата в цената, което вече ще превърне спестяванията в инвестиция, а доходността доста прилична, имайки предвид дългите години, в които сме получавали наем.
В заключние можем да кажем, че покупката на втори имот с ипотека осигурява доста по-добра защита на спестяванията от банковия депозит или животозастраховката, стига договорът за кредит да бъде разумен и подходящ. Това вече зависи от нас, като консултанти по лични и фирмени финанси, а в този вид съветване имаме над 19 години опит, който сме готови да споделим в детайли на нашите клиенти.
Imagine that all of us—all of society—have landed on some alien planet and need to form a government: clean slate. We do not have any legacy systems from the United States or any other country. We do not have any special or unique interests to perturb our thinking. How would we govern ourselves? It is unlikely that we would use the systems we have today. Modern representative democracy was the best form of government that eighteenth-century technology could invent. The twenty-first century is very different: scientifically, technically, and philosophically. For example, eighteenth-century democracy was designed under the assumption that travel and communications were both hard.
Indeed, the very idea of representative government was a hack to get around technological limitations. Voting is easier now. Does it still make sense for all of us living in the same place to organize every few years and choose one of us to go to a single big room far away and make laws in our name? Representative districts are organized around geography because that was the only way that made sense two hundred-plus years ago. But we do not need to do it that way anymore. We could organize representation by age: one representative for the thirty-year-olds, another for the forty-year-olds, and so on. We could organize representation randomly: by birthday, perhaps. We can organize in any way we want. American citizens currently elect people to federal posts for terms ranging from two to six years. Would ten years be better for some posts? Would ten days be better for others? There are lots of possibilities. Maybe we can make more use of direct democracy by way of plebiscites. Certainly we do not want all of us, individually, to vote on every amendment to every bill, but what is the optimal balance between votes made in our name and ballot initiatives that we all vote on?
For the past three years, I have organized a series of annual two-day workshops to discuss these and other such questions.1 For each event, I brought together fifty people from around the world: political scientists, economists, law professors, experts in artificial intelligence, activists, government types, historians, science-fiction writers, and more. We did not come up with any answers to our questions—and I would have been surprised if we had—but several themes emerged from the event. Misinformation and propaganda was a theme, of course, and the inability to engage in rational policy discussions when we cannot agree on facts. The deleterious effects of optimizing a political system for economic outcomes was another theme. Given the ability to start over, would anyone design a system of government for the near-term financial interest of the wealthiest few? Another theme was capitalism and how it is or is not intertwined with democracy. While the modern market economy made a lot of sense in the industrial age, it is starting to fray in the information age. What comes after capitalism, and how will it affect the way we govern ourselves?
Many participants examined the effects of technology, especially artificial intelligence (AI). We looked at whether—and when—we might be comfortable ceding power to an AI system. Sometimes deciding is easy. I am happy for an AI system to figure out the optimal timing of traffic lights to ensure the smoothest flow of cars through my city. When will we be able to say the same thing about the setting of interest rates? Or taxation? How would we feel about an AI device in our pocket that voted in our name, thousands of times per day, based on preferences that it inferred from our actions? Or how would we feel if an AI system could determine optimal policy solutions that balanced every voter’s preferences: Would it still make sense to have a legislature and representatives? Possibly we should vote directly for ideas and goals instead, and then leave the details to the computers.
These conversations became more pointed in the second and third years of our workshop, after generative AI exploded onto the internet. Large language models are poised to write laws, enforce both laws and regulations, act as lawyers and judges, and plan political strategy. How this capacity will compare to human expertise and capability is still unclear, but the technology is changing quickly and dramatically. We will not have AI legislators anytime soon, but just as today we accept that all political speeches are professionally written by speechwriters, will we accept that future political speeches will all be written by AI devices? Will legislators accept AI-written legislation, especially when that legislation includes a level of detail that human-based legislation generally does not? And if so, how will that change affect the balance of power between the legislature and the administrative state? Most interestingly, what happens when the AI tools we use to both write and enforce laws start to suggest policy options that are beyond human understanding? Will we accept them, because they work? Or will we reject a system of governance where humans are only nominally in charge?
Scale was another theme of the workshops. The size of modern governments reflects the technology at the time of their founding. European countries and the early American states are a particular size because that was a governable size in the eighteenth and nineteenth centuries. Larger governments—those of the United States as a whole and of the European Union—reflect a world where travel and communications are easier. Today, though, the problems we have are either local, at the scale of cities and towns, or global. Do we really have need for a political unit the size of France or Virginia? Or is it a mixture of scales that we really need, one that moves effectively between the local and the global?
As to other forms of democracy, we discussed one from history and another made possible by today’s technology. Sortition is a system of choosing political officials randomly. We use it today when we pick juries, but both the ancient Greeks and some cities in Renaissance Italy used it to select major political officials. Today, several countries—largely in Europe—are using the process to decide policy on complex issues. We might randomly choose a few hundred people, representative of the population, to spend a few weeks being briefed by experts, debating the issues, and then deciding on environmental regulations, or a budget, or pretty much anything.
“Liquid democracy” is a way of doing away with elections altogether. The idea is that everyone has a vote and can assign it to anyone they choose. A representative collects the proxies assigned to him or her and can either vote directly on the issues or assign all the proxies to someone else. Perhaps proxies could be divided: this person for economic matters, another for health matters, a third for national defense, and so on. In the purer forms of this system, people might transfer their votes to someone else at any time. There would be no more election days: vote counts might change every day.
And then, there is the question of participation and, more generally, whose interests are taken into account. Early democracies were really not democracies at all; they limited participation by gender, race, and land ownership. These days, to achieve a more comprehensive electorate we could lower the voting age. But, of course, even children too young to vote have rights, and in some cases so do other species. Should future generations be given a “voice,” whatever that means? What about nonhumans, or whole ecosystems? Should everyone have the same volume and type of voice? Right now, in the United States, the very wealthy have much more influence than others do. Should we encode that superiority explicitly? Perhaps younger people should have a more powerful vote than everyone else. Or maybe older people should.
In the workshops, those questions led to others about the limits of democracy. All democracies have boundaries limiting what the majority can decide. We are not allowed to vote Common Knowledge out of existence, for example, but can generally regulate speech to some degree. We cannot vote, in an election, to jail someone, but we can craft laws that make a particular action illegal. We all have the right to certain things that cannot be taken away from us. In the community of our future, what should be our rights as individuals? What should be the rights of society, superseding those of individuals?
Personally, I was most interested, at each of the three workshops, in how political systems fail. As a security technologist, I study how complex systems are subverted—hacked, in my parlance—for the benefit of a few at the expense of the many. Think of tax loopholes, or tricks to avoid government regulation. These hacks are common today, and AI tools will make them easier to find—and even to design—in the future. I would want any government system to be resistant to trickery. Or, to put it another way: I want the interests of each individual to align with the interests of the group at every level. We have never had a system of government with this property, but—in a time of existential risks such as climate change—it is important that we develop one.
Would this new system of government even be called “democracy”? I truly do not know.
Such speculation is not practical, of course, but still is valuable. Our workshops did not produce final answers and were not intended to do so. Our discourse was filled with suggestions about how to patch our political system where it is fraying. People regularly debate changes to the US Electoral College, or the process of determining voting districts, or the setting of term limits. But those are incremental changes. It is difficult to find people who are thinking more radically: looking beyond the horizon—not at what is possible today but at what may be possible eventually. Thinking incrementally is critically important, but it is also myopic. It represents a hill-climbing strategy of continuous but quite limited improvements. We also need to think about discontinuous changes that we cannot easily get to from here; otherwise, we may be forever stuck at local maxima. And while true innovation in politics is a lot harder than innovation in technology, especially without a violent revolution forcing changes on us, it is something that we as a species are going to have to get good at, one way or another.
Our workshop will reconvene for a fourth meeting in December 2025.
Note
The First International Workshop on Reimagining Democracy (IWORD) was held December 7—8, 2022. The Second IWORD was held December 12—13, 2023. Both took place at the Harvard Kennedy School. The sponsors were the Ford Foundation, the Knight Foundation, and the Ash and Belfer Centers of the Kennedy School. See Schneier, “Recreating Democracy” and Schneier, “Second Interdisciplinary Workshop.”
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.