Мудният асансьор на властта в България

Post Syndicated from Емилия Милчева original https://www.toest.bg/mudniyat-asansyor-na-vlastta-v-bulgaria/

Мудният асансьор на властта в България

Много имена в кандидатдепутатските листи за изборите на 27 октомври ще предизвикат у избирателите досада, отвращение и апатия. И за това си има основателна причина (освен втръсналата честота на изборите): асансьорът на властта в България е заседнал между 1989 г. и началото на XXI век. Тогава се формираха зависимостите, чадърите, обръчите – и първите милиони, преразпределяха се държавните активи. Макар тези процеси да са приключили, а геополитическата ориентация на България да е променена, политиците, които са ги покровителствали, не бързат да напуснат сцената. Някои го направиха, но партийни апаратчици все така блокират асансьора на последния етаж. 

Социалната мобилност и ротацията, благодарение на които една политическа сила се обновява, отсъстват в системните български партии. Отсъства и вътрешнопартийната демокрация. Антисистемните също заимстват тези практики. Трудно е нови хора с идеи да се изкачат на върха, а от него да слязат други, ако тези механизми са блокирани. Затова и обновлението е толкова мъчително и ако се случи, то е с шут от върха – както наблюдаваме в БСП и в ДПС, но също и в ГЕРБ. По-рядко е с подаване на оставка, както направи съпредседателят на „Демократична България“ Христо Иванов заради слабите изборни резултати на ПП–ДБ. Сега на партията му „Да, България“ предстои избор на нов лидер. 

Още по-рано обаче, през май 2013 г., когато коалицията между „Демократи за силна България“ и „Български демократичен форум“ не мина 4-процентната бариера на изборите, лидерът на ДСБ Иван Костов подаде оставка заедно с националното ръководство на партията и се оттегли от активната политика. Тогава Петър Москов каза:

С оттеглянето на Костов последният голям лидер напуска политиката.

И президентът Георги Първанов се оттегли в края на 2016 г. от лидерския пост в АБВ – партията, която създаде, след като Националният съвет на БСП го изключи заедно с още няколко функционери през 2014 г. „Правим крачка назад, за да дадем път на младите“, каза той тогава. АБВ обаче не се подмлади особено.

Причините за съпротивата у политическата върхушка в България да освободи позиции могат да се обобщят така: концентрация на власт и влияние, преплитане на неформални мрежи и зависимости, липса на вътрешнопартийна демокрация, спад на общественото доверие и апатия. Към това се прибавят неразвитата демократична култура и наследството на политическата инерция от тоталитаризма, когато лидерите заедно с велможите си оставаха на власт десетилетия.

Старите елити сключват и пакт за ненападение помежду си, един по-комплициран вариант на „гарван гарвану око не вади“. Разбира се, примирието се крепи не на джентълменско споразумение, а на държани „на трупчета“ дела от прокуратурата – застраховка срещу „борбата с корупцията“.

Концентрация на власт и неформални мрежи

В старите политически елити са концентрирани власт, влияние и ресурси. Вижте БСП и ДПС. Тази власт включва не само политически постове, но и икономически връзки, медийна подкрепа и обществени контакти. Така те успяват да съхранят позициите си и да попречат на влизането на нови и несвързани с тях лица, които биха могли да се противопоставят на установения модел. Ако подобни хора все пак биват допуснати, те са лични номинации на лидера, поради което на практика промяна няма как да се осъществи. Например кариерата си в БСП Иван Ченчев, Калоян Методиев и Крум Дончев дължат на личното покровителство на Нинова, както и впрочем някои от организаторите на вътрешния преврат, като Ангел Зафиров, временно и.ф. председател. Той и доскорошната ѝ партийна свита постъпиха с Нинова така, както тя с опозиционерите си. 

Но и социалистите си позволяват волности. Софийската организация на БСП например е номинирала за кандидат-депутати от гражданската квота доцентката по конституционно право Наталия Киселова и известния с прозвището „Лорд“ Евгени Минчев – пиар, светска персона и защитник на поправката в Закона за предучилищното и училищното образование, забраняваща ЛГБТ пропагандата в училище.

Липсата на реална вътрешнопартийна демокрация скъсява кадровата скамейка на партиите. Там седят любимците на лидера, макар и изхабени от употреба, като Йорданка Фандъкова от ГЕРБ например, най-дълго управлявалият кмет на София – от есента на 2009-та до октомври 2023-та. Или завърналата се като депутат в 50-тия парламент Цвета Караянчева, шест пъти избирана с листата на ГЕРБ за народна представителка.

Вървят спекулации, че този път лидерът Борисов ще остави на заден план бившите министри и хора като Любен Дилов, чиято добавена стойност е в смешките от трибуната. Водачи на листи ще са успешни кметове на ГЕРБ, като Живко Тодоров (Стара Загора) и Димитър Николов (Бургас), които се харесват много повече от партийните бюрократи. Дали после ще се върнат на кметските си постове, или ще останат в парламента, ще реши отново Бойко Борисов. Целта, която той обяви, е минимум 70, максимум 80 депутати в 51-вия парламент. В настоящия коалираната със СДС партия има 68. 

Петнайсета година Борисов управлява ГЕРБ, концентрирайки в ръцете си огромно влияние и ресурси и въпреки че ГЕРБ са машина за избори и рядко са губили първото място, зависимостите на лидера вече тежат на партията. Обвързаностите му с олигарха Делян Пеевски, чието име е нарицателно за задкулисие, са сред причините ПП–ДБ да се въздържат от коалиция с ГЕРБ, освен ако тези връзки не бъдат прекратени. 

Политиката в България е силно свързана с неформални мрежи от бизнесмени, обществени фигури и дори престъпни групировки. В системата от зависимости, която те с общи усилия създават, е много трудно да се утвърдят нови и независими кандидати, защото не могат да разчитат на същите връзки и подкрепа, а още не са изградили свои. 

Силно привързани към властта

Ние, ДСБ, не сме публика. Не приемаме политиката за сцена. ДСБ предлагаме на обществото силни идеи и принципи, ясни цели и критерий, по който да оценява своето управление. 

Тези думи са от реч на Иван Костов година преди да се оттегли от реалната политика. 

Затова пък на настоящия председател на ДСБ и съпредседател на „Демократична България“ Атанас Атанасов и през ум не му минава да си тръгне. Заявката, че няма да подаде оставка след изборите на 9 юни, когато ПП–ДБ изгубиха половината си избиратели, а спадът започна от по-рано, той мотивира със запазения брой депутати на ДСБ. Тази бройка обаче се дължи на ловкост и договорки с ПП при подреждането на листите, а не на активността и енергията на „Демократи за силна България“. 

В БСП пък разбират асансьора на властта като рециклиране на стари другари на челни места в листите. Мая Манолова от „Изправи се, БГ“ и Румен Петков от АБВ декларираха отказ, но не и Костадин Паскалев, Татяна Дончева, Кирил Добрев, също и бившият председател на БСП Сергей Станишев, който при всяка медийна изява – а те зачестиха напоследък, напомня, че не би отказал да оглави листа. (Решението за водачите ще вземе Националният съвет на БСП до дни.)

Станишев приключи с лидерството на Партията на европейските социалисти, също и с Европарламента, и се бори да се завърне в политиката (в България), което може да му осигури депутатско място в 51-вото НС. За осми пореден път там по всяка вероятност ще бъде и бизнесменът Петър Кънев, отново от листата в Бургас, заедно с друга червена номенклатура като Кристиян Вигенин, Зафиров, Борислав Гуцанов… 

Всички те се ослушват дали няма да ги огрее възможността отново да се включат във властта, след като Борисов посочи БСП и „Има такъв народ“ като възможни партньори за коалиционно управление, наред с известните от сглобката ПП–ДБ и ДПС (без да поясни кое ДПС). Зависимостите на Станишев от Пеевски не са тайна не само заради „Ако не изберем Пеевски, правителството пада“ – възходът на Пеевски започна именно при кабинета на Тройната коалиция, оглавяван от Станишев. С ГЕРБ, но и с Пеевски прекрасно си колаборира и друга бивша номенклатура на „Позитано“ 20 – Кирил Добрев. 

Скоро всички листи ще са готови за изборите на 27 октомври. 

Дали тези хора знаят накъде да поведат България…
How Cloudflare is helping domain owners with the upcoming Entrust CA distrust by Chrome and Mozilla

Post Syndicated from Dina Kozlov original https://blog.cloudflare.com/how-cloudflare-is-helping-domain-owners-with-the-upcoming-entrust-ca

Chrome and Mozilla announced that they will stop trusting Entrust’s public TLS certificates issued after November 12, 2024 and December 1, 2024, respectively. This decision stems from concerns related to Entrust’s ability to meet the CA/Browser Forum’s requirements for a publicly trusted certificate authority (CA). To prevent Entrust customers from being impacted by this change, Entrust has announced that they are partnering with SSL.com, a publicly trusted CA, and will be issuing certs from SSL.com’s roots to ensure that they can continue to provide their customers with certificates that are trusted by Chrome and Mozilla. 

We’re excited to announce that we’re going to be adding SSL.com as a certificate authority that Cloudflare customers can use. This means that Cloudflare customers that are currently relying on Entrust as a CA and uploading their certificate manually to Cloudflare will now be able to rely on Cloudflare’s certificate management pipeline for automatic issuance and renewal of SSL.com certificates. 

CA distrust: responsibilities, repercussions, and responses

With great power comes great responsibility
Every publicly trusted certificate authority (CA) is responsible for maintaining a high standard of security and compliance to ensure that the certificates they issue are trustworthy. The security of millions of websites and applications relies on a CA’s commitment to these standards, which are set by the CA/Browser Forum, the governing body that defines the baseline requirements for certificate authorities. These standards include rules regarding certificate issuance, validation, and revocation, all designed to secure the data transferred over the Internet. 

However, as with all complex software systems, it’s inevitable that bugs or issues may arise, leading to the mis-issuance of certificates. Improperly issued certificates pose a significant risk to Internet security, as they can be exploited by malicious actors to impersonate legitimate websites and intercept sensitive data. 

To mitigate such risk, publicly trusted CAs are required to communicate issues as soon as they are discovered, so that domain owners can replace the compromised certificates immediately. Once the issue is communicated, CAs must revoke the mis-issued certificates within 5 days to signal to browsers and clients that the compromised certificate should no longer be trusted. This level of transparency and urgency around the revocation process is essential for minimizing the risk posed by compromised certificates. 

Why Chrome and Mozilla are distrusting Entrust
The decision made by Chrome and Mozilla to distrust Entrust’s public TLS certificates stems from concerns regarding Entrust’s incident response and remediation process. In several instances, Entrust failed to report critical issues and did not revoke certificates in a timely manner. The pattern of delayed action has eroded the browsers’ confidence in Entrust’s ability to act quickly and transparently, which is crucial for maintaining trust as a CA. 

Google and Mozilla cited the ongoing lack of transparency and urgency in addressing mis-issuances as the primary reason for their distrust decision. Google specifically pointed out that over the past 6 years, Entrust has shown a “pattern of compliance failures” and failed to make the “tangible, measurable progress” necessary to restore trust. Mozilla echoed these concerns, emphasizing the importance of holding Entrust accountable to ensure the integrity and security of the public Internet. 

Entrust’s response to the distrust announcement 
In response to the distrust announcement from Chrome and Mozilla, Entrust has taken proactive steps to ensure continuity for their customers. To prevent service disruption, Entrust has announced that they are partnering with SSL.com, a CA that’s trusted by all major browsers, including Chrome and Mozilla, to issue certificates for their customers. By issuing certificates from SSL.com’s roots, Entrust aims to provide a seamless transition for their customers, ensuring that they can continue to obtain certificates that are recognized and trusted by the browsers their users rely on. 

In addition to their partnership with SSL.com, Entrust stated that they are working on a number of improvements, including changes to their organizational structure, revisions to their incident response process and policies, and a push towards automation to ensure compliant certificate issuances. 

How Cloudflare can help Entrust customers 

Now available: SSL.com as a certificate authority for Advanced Certificate Manager and SSL for SaaS certificates
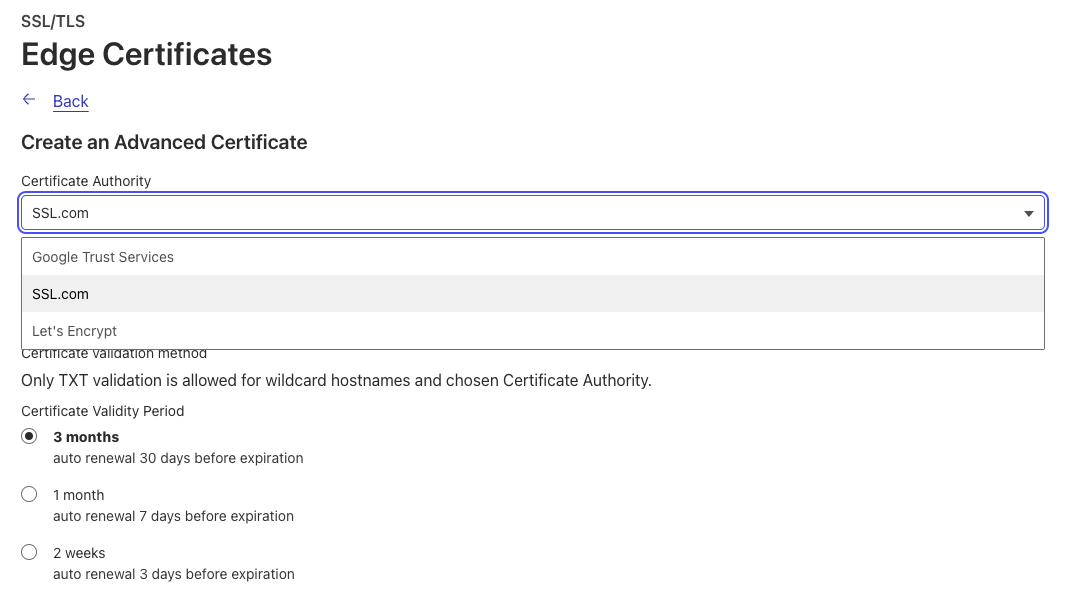
We’re excited to announce that customers using Advanced Certificate Manager will now be able to select SSL.com as a certificate authority for Advanced certificates and Total TLS certificates. Once the certificate is issued, Cloudflare will handle all future renewals on your behalf. 

By default, Cloudflare will issue SSL.com certificates with a 90 day validity period. However, customers using Advanced Certificate Manager will have the option to set a custom validity period (14, 30, or 90 days) for their SSL.com certificates. In addition, Enterprise customers will have the option to obtain 1-year SSL.com certificates. Every SSL.com certificate order will include 1 RSA and 1 ECDSA certificate.

Note: We are gradually rolling this out and customers should see the CA become available to them through the end of September and into October. 

If you’re using Cloudflare as your DNS provider, there are no additional steps for you to take to get the certificate issued. Cloudflare will validate the ownership of the domain on your behalf to get your SSL.com certificate issued and renewed. 

If you’re using an external DNS provider and have wildcard hostnames on your certificates, DNS based validation will need to be used, which means that you’ll need to add TXT DCV tokens at your DNS provider in order to get the certificate issued. With SSL.com, two tokens are returned for every hostname on the certificate. This is because SSL.com uses different tokens for the RSA and ECDSA certificates. To reduce the overhead around certificate management, we recommend setting up DCV Delegation to allow Cloudflare to place domain control validation (DCV) tokens on your behalf. Once DCV Delegation is set up, Cloudflare will automatically issue, renew, and deploy all future certificates for you. 

Advanced Certificates: selecting SSL.com as a CA through the UI or API
Customers can select SSL.com as a CA through the UI or through the Advanced Certificate API endpoint by specifying “ssl_com” in the certificate_authority parameter. 

If you’d like to use SSL.com as a CA for an advanced certificate, you can select “SSL.com” as your CA when creating a new Advanced certificate order. 


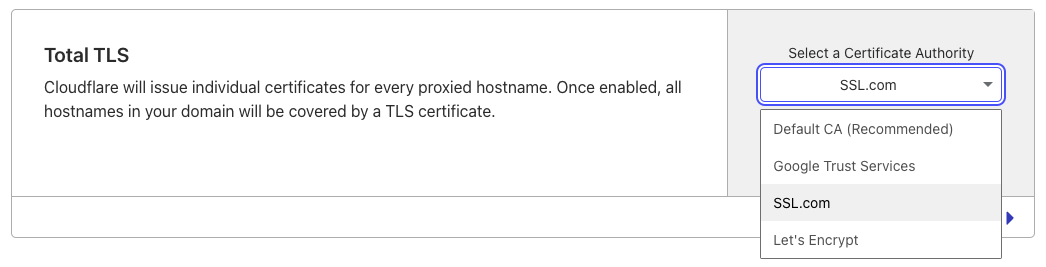
If you’d like to use SSL.com as a CA for all of your certificates, we recommend setting your Total TLS CA to SSL.com. This will issue an individual certificate for each of your proxied hostname from the CA. 

Note: Total TLS is a feature that’s only available to customers that are using Cloudflare as their DNS provider. 


SSL for SaaS: selecting SSL.com as a CA through the UI or API
Enterprise customers can select SSL.com as a CA through the custom hostname creation UI or through the Custom Hostnames API endpoint by specifying “ssl_com” in the certificate_authority parameter. 

All custom hostname certificates issued from SSL.com will have a 90 day validity period. If you have wildcard support enabled for custom hostnames, we recommend using DCV Delegation to ensure that all certificate issuances and renewals are automatic.  

Our recommendation if you’re using Entrust as a certificate authority 

Cloudflare customers that use Entrust as their CA are required to manually handle all certificate issuances and renewals. Since Cloudflare does not directly integrate with Entrust, customers have to get their certificates issued directly from the CA and upload them to Cloudflare as custom certificates. Once these certificates come up for renewal, customers have to repeat this manual process and upload the renewed certificates to Cloudflare before the expiration date. 

Manually managing your certificate’s lifecycle is a time-consuming and error prone process. With certificate lifetimes decreasing from 1 year to 90 days, this cycle needs to be repeated more frequently by the domain owner. 

As Entrust transitions to issuing certificates from SSL.com roots, this manual management process will remain unless customers switch to Cloudflare’s managed certificate pipeline. By making this switch, you can continue to receive SSL.com certificates without the hassle of manual management — Cloudflare will handle all issuances and renewals for you!

In early October, we will be reaching out to customers who have uploaded Entrust certificates to Cloudflare to recommend migrating to our managed pipeline for SSL.com certificate issuances, simplifying your certificate management process. 

If you’re ready to make the transition today, simply go to the SSL/TLS tab in your Cloudflare dashboard, click “Order Advanced Certificate”, and select “SSL.com” as your certificate authority. Once your new SSL.com certificate is issued, you can either remove your Entrust certificate or simply let it expire. Cloudflare will seamlessly transition to serving the managed SSL.com certificate before the Entrust certificate expires, ensuring zero downtime during the switch. 

Вместо подкрепа – преследване. Защо България се проваля в борбата с употребата на наркотици

Post Syndicated from Надежда Цекулова original https://www.toest.bg/zashto-bulgaria-se-provalya-v-borbata-s-upotrebata-na-narkotitsi/

Вместо подкрепа – преследване. Защо България се проваля в борбата с употребата на наркотици

Неотдавна млада певица, рекламираща енергийни прахчета за шмъркане, предизвика взрив от публично недоволство. Рекламата беше свалена, певицата обяви, че „се самоканселира“, и темата потъна със скоростта, с която беше грабнала вниманието на публиката. Истински, задълбочен и отговорен разговор за употребата на наркотици и за предотвратяването на тази употреба отново не се проведе.

В следващите редове ще маркираме какви биха били основните спирки на един такъв разговор, без претенцията да го обхванем напълно, но с надеждата поне да посеем началото му. Юлия Георгиева е председател на Фондация „Център за хуманни политики“. Организацията се занимава с дейности за намаляване на вредите от употребата на наркотици и управлява единствения в страната нископрагов център за работа с хора, зависими от наркотици и алкохол – Розовата къща. С нея разговаря Надежда Цекулова.

Вие бяхте човекът, който неотдавна обърна внимание на реклама на енергийни прахчета за шмъркане, и това предизвика грандиозен публичен скандал. Но тази реклама не беше нито нова, нито единствена и вероятно хиляди хора са я видели преди Вашата реакция. И не са се впечатлили силно. Други пък и след скандала недоумяваха какъв е проблемът – нали прахчетата са безвредни. Нека започнем с тази тема с все още отекващо ехо и с обяснението защо рекламирането на прахчета за шмъркане носи рискове.

Проблемът с наркотиците никога не е веществото, а е защо хората искат да вземат наркотици. Какво им дават тези вещества. Популярните лица помагат за създаването на магия около употребата на дадено нещо. В конкретния случай – пред шмъркането по принцип има психологическа бариера, тъй като в нашата култура обичайно нищо не се приема по този начин, за нас то е неестествено. Прескачането на тази граница, на този естествен страх, който е една от бариерите пред един млад човек да започне да взема наркотици, е проблемно. Нормализирането и създаването на магия около употребата драстично повишава риска да се премине от едно вещество към друго.

И пак казвам, веществото няма значение. Значение има всичко останало. Значение има например това, че дамата, чието име беше забъркано в скандала, така и не разбра какво предизвика острата реакция срещу рекламата. А тя не го разбра, защото такъв е нейният свят. Около нея очевидно така се прави, то е нормализирано. Това е страшното в цялата история.

Свалянето на тази реклама за кратко повдигна темата за превенцията на употребата на наркотици, но много бързо тази вълна отмина. А като че ли въпросът какво е работеща превенция и има ли тя почва у нас се нуждае от по-сериозен дебат… 

Идеята на превенцията е децата да се чувстват достатъчно спокойни да говорят по темата и ако им се появят мераци да опитат някое вещество, да могат да ги обсъдят и да се спрат навреме. У нас често „превенция“ се прави от МВР – полицай влиза с куче в класната стая и това е най-страшното нещо на света, защото той ей сега ще пусне кучето и то ще разбере кой има у себе си трева. Това не е превенция. Това е сплашване и е най-сигурният начин детето никога да не потърси помощ. 

Идеята на превенцията е също да има истинна информация. Тук чуваме: „Ако пушиш трева, ще умреш“, но те вече са пушили трева и не са умрели, и в момента, в който излезеш с такова послание, младежите престават да ти вярват и ставаш за смях, а това води и до неглижиране на проблема. 

А как изглежда качествената превенция?

Трябва да се обхващат различните групи спрямо техния риск. Ако отдалечим фокуса, борбата с наркотиците, както се нарича в България, се дели на две основни групи: борба с търсенето и борба с предлагането. Четирите основни стълба за борба с наркотиците са: превенция; терапия и рехабилитация; намаляване на вредите; преследване на трафика и разпространението. Те трябва да бъдат равни и като тежест, и като финансиране. В България за шест години имаше отделени 500 млн. лева за преследване и 50 млн. лева за всичко останало. И всъщност тук вече се вижда как нещата се изкривяват, защото, когато има търсене, винаги ще има и предлагане. Хората трябва да имат по-малко причини да употребяват наркотици, защото това се случва в отговор на определени нужди. Никой не започва с идеята „Аз защо пък да не стана зависим?“. 

Има ли някакви доминиращи причини за употреба на наркотици?

Могат да бъдат много различни. Например крайна бедност – неслучайно сегрегираните райони са много силно засегнати, това е начин да оцелееш психически. А може да е и за забавление. Може да е нужда да бъдеш част от някаква среда. И е важно да се работи с тези причини. Така стигаме до добрата превенция. Ние от години искаме да се въведе такава програма в България. Тя работи с конкретни психични нужди сред младите хора и се спира на четири основни неща, които са маркери за риск: импулсивно поведение, тревожност, депресивност и търсене на силни усещания. Тези рискови фактори се установяват чрез въпросник и последващата работа се насочва към децата, които реално са рискови.

Има ли данни колко са те?

Средно 20–30%, въпреки че за България излязоха повече – около 50%. Има високи показатели и в други страни, където децата по-трудно намират мястото си в обществото. У нас го отдавам на това, че ние не сме много подкрепящи хора, ние от българския етнос. Сблъсквала съм се със стотици случаи, в които единият родител знае, че детето има проблем с наркотици, другият не знае, а всички живеят заедно. Докато в ромската общност например става съвсем обратното – ако човек, който употребява наркотици, се прибере вкъщи и каже: „Аз искам да спра“, там веднага се вдига телефонът, събират се 30 човека, обграждат го отвсякъде и се грижат за него. Изключително различно е и е много впечатляваща разликата, защото живеем на една и съща територия. 

Но да се върна на въпроса. Да кажем, че до 30% от хлапетата са рискови. С тях се работи в групи, в които всъщност не се говори за наркотици. Говори се за чувства, говори се за това какво и как точно ти пречи – ако например си импулсивен и си се опитал да удариш учителката, това по какъв начин ти влияе и защо не е хубаво да го правиш. И когато се чувстваш така, какво би могъл да направиш, за да се справиш. Тези казуси се обсъждат в групата от млади хора с помощта на фасилитатор, но те сами си търсят решенията, не им ги дава някой назидателен възрастен. В страните, в които тази програма работи, има доста висок процент на успеваемост.

При отсъствието на ефективна превенция очевидно много деца и младежи опитват разнообразни вещества. Какво се случва след това?

След това се обособяват две групи. В едната са младежите, които са опитали някакво вещество еднократно – в това, общо взето, няма проблем, стига да знаят какво точно пробват. В другата са тези, които са започнали да употребяват редовно, и тук историята става зловеща. Те имат нужда от терапия, рехабилитация и нашата цел е, докато са деца и млади хора, да спрат употребата.

В България обаче има само една терапевтична общност, в която приемат младежи под 18 г., и тя е платена. В това няма нищо лошо и доколкото знам, работят добре. Просто е много скъпо за семействата и съответно за най-рисковите деца е абсолютно недостъпно. Ние в момента имаме едно дете, което е в болница в изключително тежко състояние. По принцип не работим с деца, но се обръщат към нас, тъй като няма към кой друг, и аз се чувствам ужасно безпомощна и гневна, защото няма какво да направя за тези деца, няма къде да ги насоча, няма система, която да ги поеме и да гарантира грижа за тях. 

Какво се случва с такива деца?

Имаше една история преди повече от десет години за едни хлапета от „Орландовци“, които бяха заразени с ХИВ. Това беше общност от деца на по 12–13 години, които си инжектираха хероин и бяха успели помежду си да се заразят с ХИВ. Стана голям скандал, имаше множество медийни публикации. Много хора от администрацията се ангажираха и положиха усилия да направят нещо за тези деца, но това така и не сработи. Всички починаха впоследствие, едно по едно. От употреба на наркотици, от ХИВ, от липса на грижа. Мисля, че в това отношение не сме мръднали през тези над десет години, независимо от изключително тежкия урок. 

По отношение на т.нар. възрастни, които са всъщност млади хора, но над 18 г., положението не е много по-добро. Има ограничен брой места, едното е в „Суходол“, в Държавната психиатрична болница за лечение на наркомании и алкохолизъм. Няма да коментирам думичката „наркомания“ – руски термин, който много отдавна трябваше да изхвърлим. Другата безплатна възможност са психиатриите – с всички ужасяващи неща, които знаем за условията и качеството на грижите в тях.

Съществуват също няколко терапевтични религиозни комуни. В тях проблемът е, че сравнително често хората отново започват да употребяват, след като напуснат комуната. Има един немалък брой терапевтични общности. Някои не са лицензирани и не подлежат на никакъв контрол. Има и такива, които работят превъзходно, но за нуждаещите се невинаги е лесно да се ориентират коя каква е. Освен това тези общности по правило също нямат финансиране и пациентът плаща между 2000 и 3000 лв. на месец, като лечението – за да има шанс за някакъв успех – продължава най-малко десет месеца. 

Има ли данни колко души са обхванати от тези възможности за терапия и рехабилитация, с всичките им условности, и колко общо се нуждаят от терапия?

Би трябвало да има някакви данни в годишния доклад на Националния фокусен център. Те отчитат някакво намаляване, но за мен не отразяват реалната ситуация. Терминологията не е осъвременена, проследяването на начина, по който се събират данните, и може би ресурсът, който се отделя за това, не са достатъчни. Като резултат аз смятам, че всъщност не знаем отговора на този въпрос. 

Вие всъщност се занимавате с намаляване на вредите от употребата на наркотици. В България преди години дейностите в това направление се развиваха и финансираха от Глобалния фонд за борба срещу СПИН, туберкулоза и малария. Откакто Фондът се оттегли от страната ни обаче, тази дейност, вместо да бъде поета от българските институции, сякаш напълно изчезна. Доколко е вярно това повърхностно впечатление? 

Във висока степен. Здравното министерство разпознава само тестване за ХИВ и за кръвнопреносими инфекции и раздаване на материали за превенцията им. Ние спечелихме една обществена поръчка за тази дейност, но парите са крайно недостатъчни. Правим го, защото имаме допълнително финансиране от Elton John AIDS Foundation и можем да си покрием разходите. Но например колегите в Пловдив трябва да работят една година с четири рискови групи за общата сума от 37 000 лв., като с тези пари трябва да наемат трима души, да купят консумативи, да платят гориво и т.н. Парите са смешни.

Говорите за мобилната си услуга. Най-разпознаваемата ви дейност обаче е Розовата къща, където оказвате доста по-широкоспектърна подкрепа. Разкажете в резюме какво предлага екипът ви там.

Винаги ще има хора, които употребяват наркотици. Ние сме там за тях, за да можем да покрием нуждите, които те имат, докато употребяват, и да ги подкрепим, ако решат да се опитат да спрат. Всъщност това е целта на нашата работа – намалявайки вредата за конкретния човек, ние намаляваме вредата за близкото му обкръжение и за обществото.

В Розовата къща специално работим с хората, които са в най-ниската възможна социална позиция. Много често те не са поддържали контакт с никакви близки хора с години, да не кажа с десетилетия. Това също е част от нашата работа. Ако този човек дойде и каже: „Аз много искам да видя майка си“, често се случва ние да се обадим на майка му и да проведем този първи разговор. И много често успяваме, защото на родителите това им тежи и искат да са полезни.

Така колелото се завърта – ако човекът се е прибрал да живее вкъщи, много по-сигурно е, че си взема лекарствата за ХИВ или за хепатит, или за каквото и да е, започва да употребява по-малко наркотици или влиза в някаква програма, започва работа. Така този човек не просто не е на улицата, а вкарва пари в бюджета и допринася за обществото. И не е задължително това да е придружено с пълно спиране на употребата.

Според мен немалко хора вярват, че или вземаш наркотици, или си социално приемлив – двете заедно са несъвместими.

Да, тук отношението е черно-бяло. Чувала съм неведнъж: „Или да спира, или да мре.“ Но аз малко ще обърна нещата. Огромна част от хората, които упражняват висококвалифицирани професии, употребяват наркотици. Огромна част от хората, на които се възхищавате, употребяват наркотици. Така приемливо и съвместимо ли звучи? В момента може би най-популярните вещества са стимулантите – вещества, които ти дават възможност да работиш повече, да бъдеш по-ефективен за по-дълъг период и една част от видимия свят на много успешни хора се крепи на тези вещества. Проблемът е, че при дълга употреба се стига до срив. 

Разказвам това, за да стане ясно, че употребата може и да не нарушава функционирането на един човек. Всеки от нас познава такива хора дори без да знае. Те имат семейства, имат социална среда, успешни са в работата си. Хората, с които Розовата къща работи обаче, са точно обратното – те са тези, които са изтеглили късата клечка, нямат нищо и никога досега не са получавали грижа и помощ. 

Защото няма друга услуга като Розовата къща?

Да. Имам тъжно-смешна история във връзка с това. Когато за първи път разбрахме, че има шанс да получим финансиране като социална услуга, и отидохме на среща в Социалното министерство, за мен беше шокиращо, когато хората от Министерството казаха: „Ние търсим подобна организация от десет години.“ Същевременно ние от десет години се занимаваме със Здравното министерство и се опитваме да обясним колко е важна работата ни, но никой не ни обръща внимание. Просто липсва всякаква координация.

Какво е положението ви в момента? Розовата къща изгуби къщата си преди няколко месеца и въпреки огромната дарителска съпричастност, опитите на Общината да ви намери ново място засега не са дали резултат. Как ще посрещнете есента? 

Столичната община успя да ни намери едно малко помещение. То категорично не може да покрие нуждите ни – няма тоалетна, няма баня, няма пералня, няма базови неща. Не можем да правим превръзки. Практически само осигуряваме храна в момента. Иначе по отношение на самото построяване на Розовата къща – най-после имаме скица от районната община и чакаме виза от главния архитект на София. Процесът върви, но за съжаление, много бавно. Идва зима и това на мен ми е най-големият кошмар. През лятото за четири месеца загубихме шест човека. Какво ще стане през зимата, не искам да мисля… 

От разговора ни дотук излиза, че нито превенцията, нито лечението, нито намаляването на вредите са ефективни у нас. Дори разпознаването на крайно рискови реклами става едва след като някой като Вас го обясни достъпно и с картинки. Каква е причината?

Щях да кажа „неглижиране“, но не е това точната дума. Точните думи са „безхаберие“ и „некадърност“. От години се опитвам да не ползвам такива силни думи, защото в системата има хора, на които им пука и които правят всичко по силите си – те не заслужават подобни обобщения. Навсякъде се намира по някой свестен и съвестен човек и благодарение на това ние не сме се сринали напълно. Но не може цялата система да се държи на мускулите на десет човека, които на местно ниво се опитват да направят нещичко за малката си общност. 

Извън тези отчайващо малко на брой хора честното обяснение е това – безхаберие и некадърност. 

Enabling conversational data discovery with LLMs at Grab

Post Syndicated from Grab Tech original https://engineering.grab.com/hubble-data-discovery

Imagine a world where finding the right data is like searching for a needle in a haystack. In today’s data-driven landscape, companies are drowning in a sea of information, struggling to navigate through countless datasets to uncover valuable insights. At Grab, we faced a similar challenge. With over 200,000 tables in our data lake, along with numerous Kafka streams, production databases, and ML features, locating the most suitable dataset for our Grabber’s use cases promptly has historically been a significant hurdle.

Problem Space

Our internal data discovery tool, Hubble, built on top of the popular open-source platform Datahub, was primarily used as a reference tool. While it excelled at providing metadata for known datasets, it struggled with true data discovery due to its reliance on Elasticsearch, which performs well for keyword searches but cannot accept and use user-provided context (i.e., it can’t perform semantic search, at least in its vanilla form). The Elasticsearch parameters provided by Datahub out of the box also had limitations: our monthly average click-through rate was only 82%, meaning that in 18% of sessions, users abandoned their searches without clicking on any dataset. This suggested that the search results were not meeting their needs.

Another indispensable requirement for efficient data discovery that was missing at Grab was documentation. Documentation coverage for our data lake tables was low, with only 20% of the most frequently queried tables (colloquially referred to as P80 tables) having existing documentation. This made it difficult for users to understand the purpose and contents of different tables, even when browsing through them on the Hubble UI.

Consequently, data consumers heavily relied on tribal knowledge, often turning to their colleagues via Slack to find the datasets they needed. A survey conducted last year revealed that 51% of data consumers at Grab took multiple days to find the dataset they required, highlighting the inefficiencies in our data discovery process.

To address these challenges and align with Grab’s ongoing journey towards a data mesh architecture, the Hubble team recognised the importance of improving data discovery. We embarked on a journey to revolutionise the way our employees find and access the data they need, leveraging the power of AI and Large Language Models (LLMs).

Vision

Given the historical context, our vision was clear: to remove humans in the data discovery loop by automating the entire process using LLM-powered products. We aimed to reduce the time taken for data discovery from multiple days to mere seconds, eliminating the need for anyone to ask their colleagues data discovery questions ever again.


Goals

To achieve our vision, we set the following goals for ourselves for the first half of 2024:

  • Build HubbleIQ: An LLM-based chatbot that could serve as the equivalent of a Lead Data Analyst for data discovery. Just as a lead is an expert in their domain and can guide data consumers to the right dataset, we wanted HubbleIQ to do the same across all domains at Grab. We also wanted HubbleIQ to be accessible where data consumers hang out the most: Slack.
  • Improve documentation coverage: A new Lead Analyst joining the team would require extensive documentation coverage of very high quality. Without this, they wouldn’t know what data exists and where. Thus, it was important for us to improve documentation coverage.
  • Enhance Elasticsearch: We aimed to tune our Elasticsearch implementation to better meet the requirements of Grab’s data consumers.

A Systematic Path to Success

Step 1: Enhance Elasticsearch

Through clickstream analysis and user interviews, the Hubble team identified four categories of data search queries that were seen either on the Hubble UI or in Slack channels:

  • Exact search: Queries belonging to this category were a substring of an existing dataset’s name at Grab, with the query length being at least 40% of the dataset’s name.
  • Partial search: The Levenshtein distance between a query in this category and any existing dataset’s name was greater than 80. This category usually comprised queries that closely resembled an existing dataset name but likely contained spelling mistakes or were shorter than the actual name.

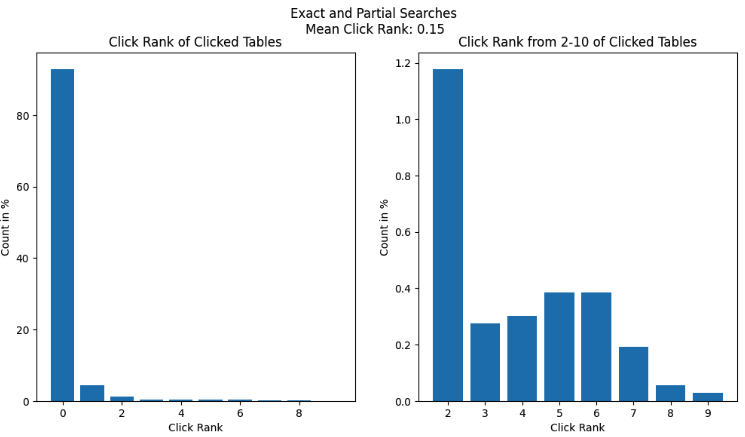
Exact and partial searches accounted for 75% of searches on Hubble (and were non-existent on Slack: as a human, receiving a message that just had the name of a dataset would feel rather odd). Given the effectiveness of vanilla Elasticsearch for these categories, the click rank was close to 0.


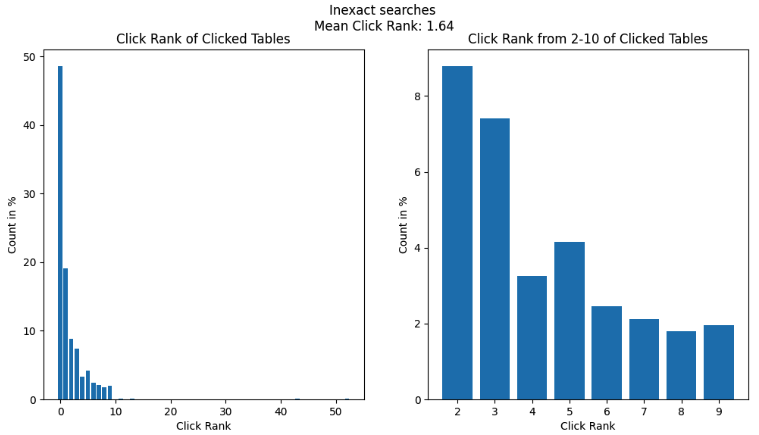
  • Inexact search: This category comprised queries that were usually colloquial keywords or phrases that may be semantically related to a given table, column, or piece of documentation (e.g., “city” or “taxi type”). Inexact searches accounted for the remaining 25% of searches on Hubble. Vanilla Elasticsearch did not perform well in this category since it relied on pure keyword matching and did not consider any additional context.

  • Semantic search: These were free text queries with abundant contextual information supplied by the user. Hubble did not see any such queries as users rightly expected that Hubble would not be able to fulfil their search needs. Instead, these queries were sent by data consumers to data producers via Slack. Such queries were numerous, but usually resulted in data hunting journeys that spanned multiple days – the root of frustration amongst data consumers.

The first two search types can be seen as “reference” queries, where the data consumer already knows what they are looking for. Inexact and contextual searches are considered “discovery” queries. The Hubble team noticed drop-offs in inexact searches because users learned that Hubble could not fulfil their discovery needs, forcing them to search for alternatives.

Through user interviews, the team discovered how Elasticsearch should be tuned to better fit the Grab context. They implemented the following optimisations:

  • Tagging and boosting P80 tables
  • Boosting the most relevant schemas
  • Hiding irrelevant datasets like PowerBI dataset tables
  • Deboosting deprecated tables
  • Improving the search UI by simplifying and reducing clutter
  • Adding relevant tags
  • Boosting certified tables

As a result of these enhancements, the click-through rate rose steadily over the course of the half to 94%, a 12 percentage point increase.

While this helped us make significant improvements to the first three search categories, we knew we had to build HubbleIQ to truly automate the last category – semantic search.

Step 2: Build a Context Store for HubbleIQ

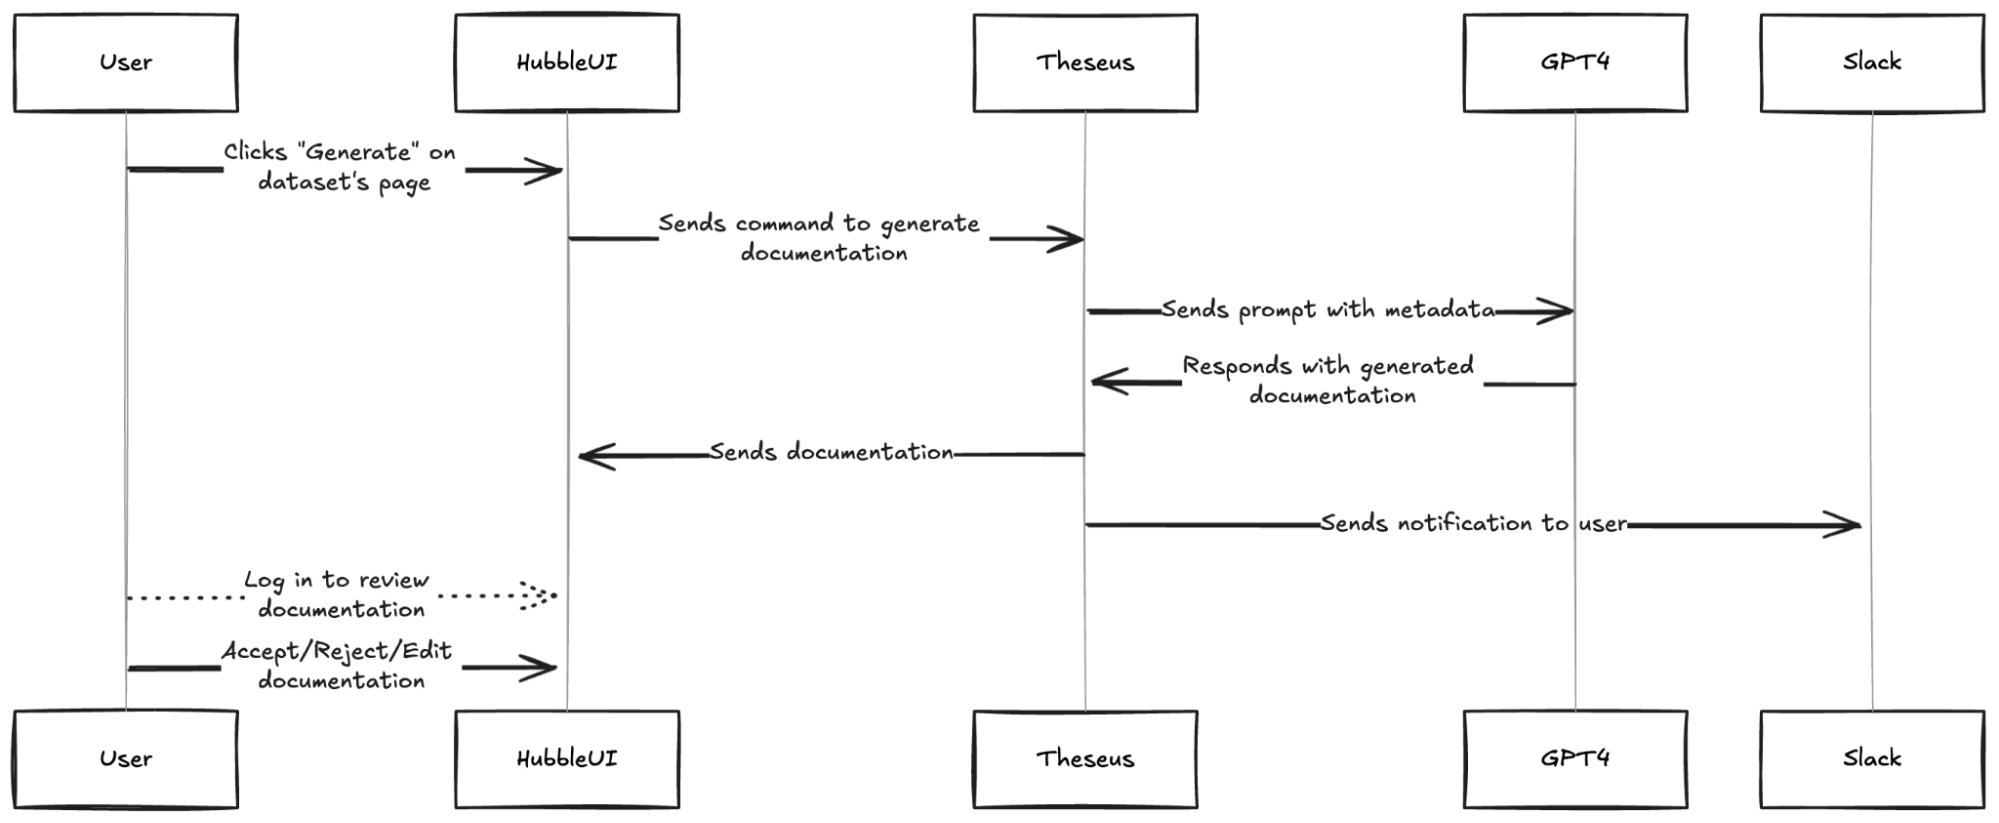
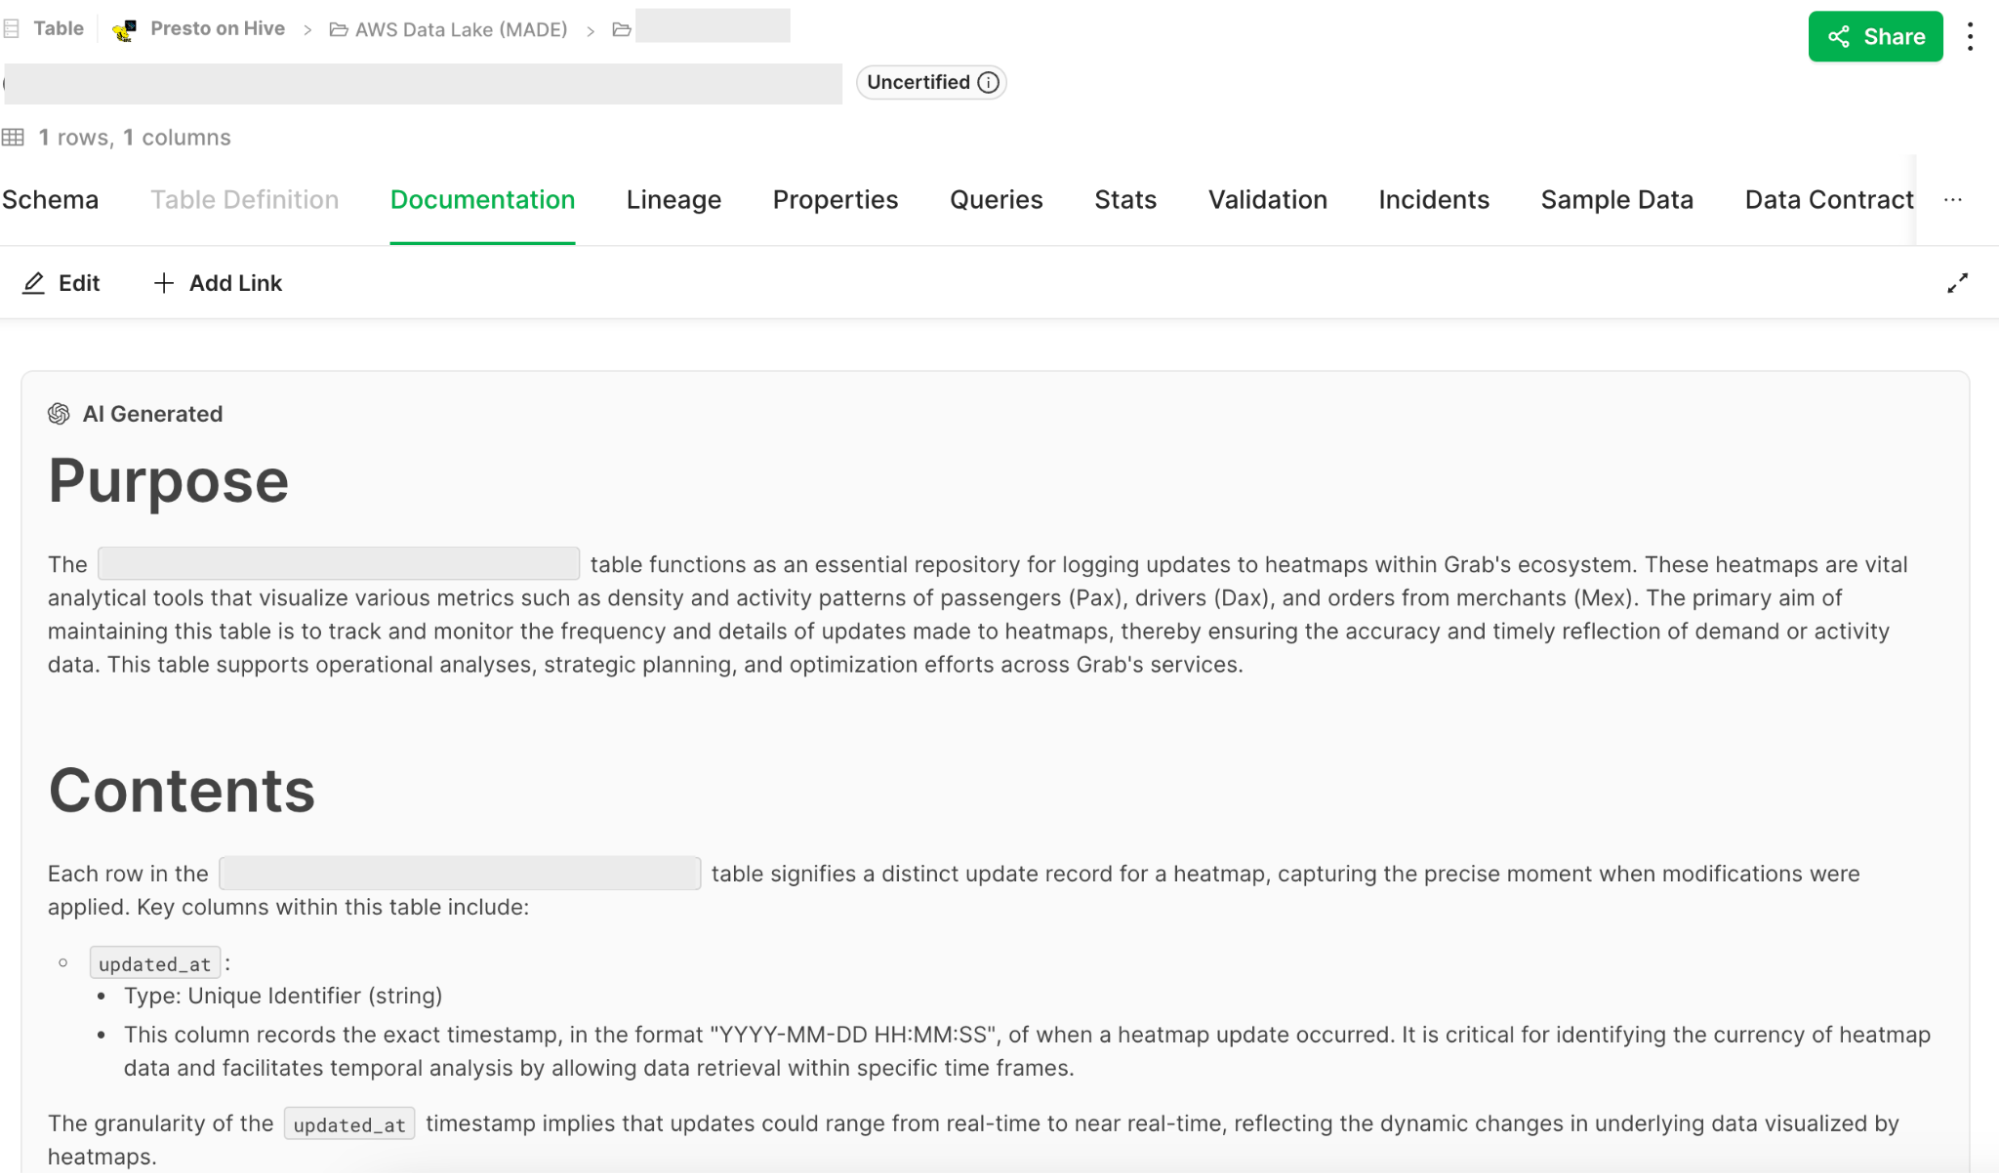
To support HubbleIQ, we built a documentation generation engine that used GPT-4 to generate documentation based on table schemas and sample data. We refined the prompt through multiple iterations of feedback from data producers.

We added a “generate” button on the Hubble UI, allowing data producers to easily generate documentation for their tables. This feature also supported the ongoing Grab-wide initiative to certify tables.


In conjunction, we took the initiative to pre-populate docs for the most critical tables, while notifying data producers to review the generated documentation. Such docs were visible to data consumers with an “AI-generated” tag as a precaution. When data producers accepted or edited the documentation, the tag was removed.


As a result, documentation coverage for P80 tables increased by 70 percentage points to ~90%. User feedback showed that ~95% of users found the generated docs useful.

Step 3: Build and Launch HubbleIQ

With high documentation coverage in place, we were ready to harness the power of LLMs for data discovery. To speed up go-to-market, we decided to leverage Glean, an enterprise search tool used by Grab.

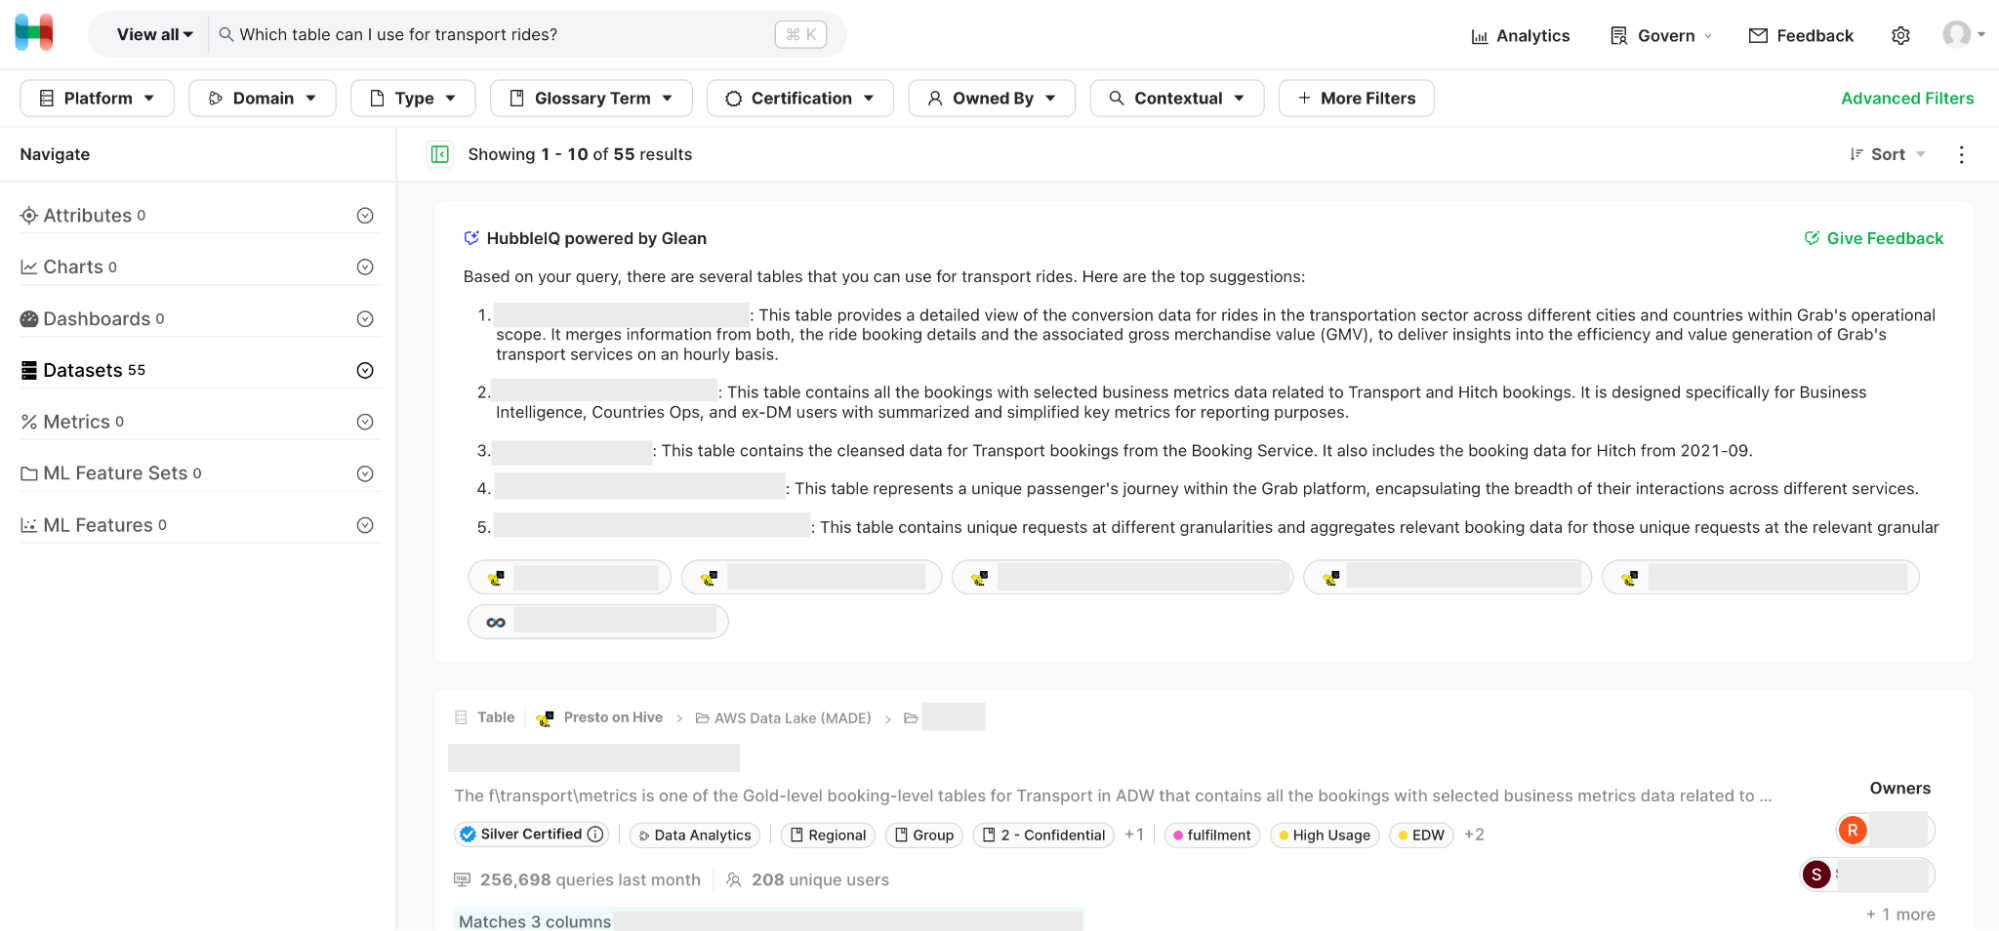
First, we integrated Hubble with Glean, making all data lake tables with documentation available on the Glean platform. Next, we used Glean Apps to create the HubbleIQ bot, which was essentially an LLM with a custom system prompt that could access all Hubble datasets that were catalogued on Glean. Finally, we integrated this bot into Hubble search, such that for any search that is likely to be a semantic search, HubbleIQ results are shown on top, followed by regular search results.


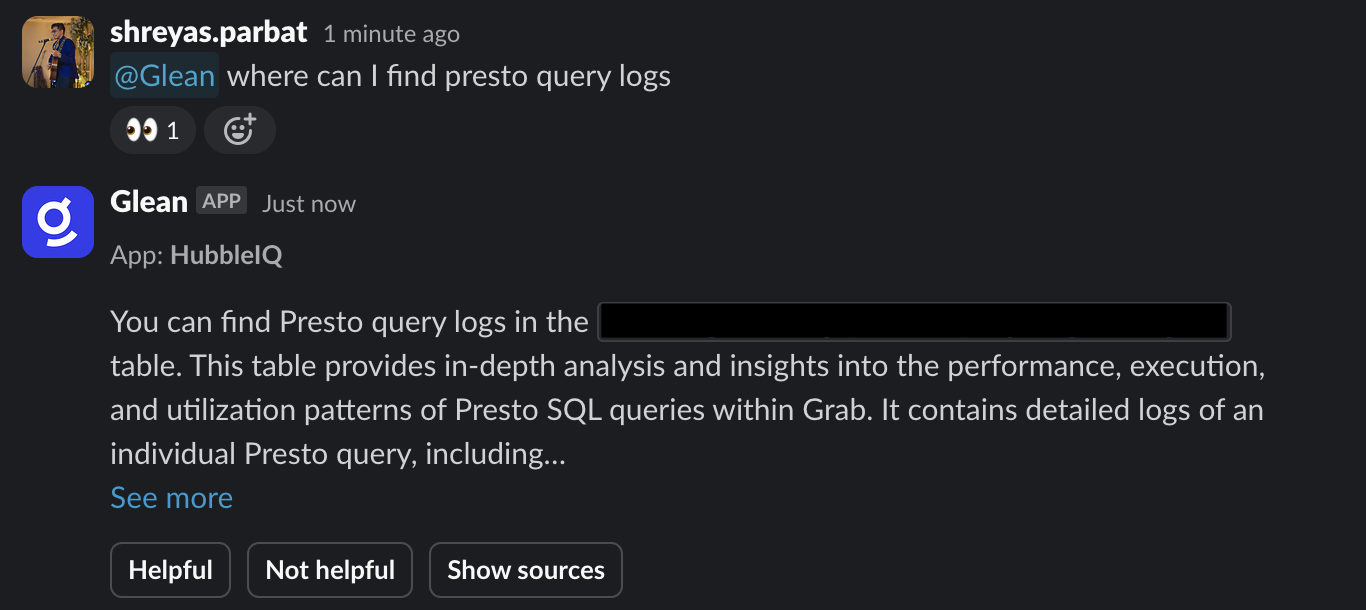
Recently, we integrated HubbleIQ with Slack, allowing data consumers to discover datasets without breaking their flow. Currently, we are working with analytics teams to add the bot to their “ask” channels (where data consumers come to ask contextual search queries for their domains). After integration, HubbleIQ will act as the first line of defence for answering questions in these channels, reducing the need for human intervention.


The impact of these improvements was significant. A follow-up survey revealed that 73% of respondents found it easy to discover datasets, marking a substantial 17 percentage point increase from the previous survey. Moreover, Hubble reached an all-time high in monthly active users, demonstrating the effectiveness of the enhancements made to the platform.

Next Steps

We’ve made significant progress towards our vision, but there’s still work to be done. Looking ahead, we have several exciting initiatives planned to further enhance data discovery at Grab.

On the documentation generation front, we aim to enrich the generator with more context, enabling it to produce even more accurate and relevant documentation. We also plan to streamline the process by allowing analysts to auto-update data docs based on Slack threads directly from Slack. To ensure the highest quality of documentation, we will develop an evaluator model that leverages LLMs to assess the quality of both human and AI-written docs. Additionally, we will implement Reflexion, an agentic workflow that utilises the outputs from the doc evaluator to iteratively regenerate docs until a quality benchmark is met or a maximum try-limit is reached.

As for HubbleIQ, our focus will be on continuous improvement. We’ve already added support for metric datasets and are actively working on incorporating other types of datasets as well. To provide a more seamless user experience, we will enable users to ask follow-up questions to HubbleIQ directly on the HubbleUI, with the system intelligently pulling additional metadata when a user mentions a specific dataset.

Conclusion

By harnessing the power of AI and LLMs, the Hubble team has made significant strides in improving documentation coverage, enhancing search capabilities, and drastically reducing the time taken for data discovery. While our efforts so far have been successful, there are still steps to be taken before we fully achieve our vision of completely replacing the reliance on data producers for data discovery. Nonetheless, with our upcoming initiatives and the groundwork we have laid, we are confident that we will continue to make substantial progress in the right direction over the next few production cycles.

As we forge ahead, we remain dedicated to refining and expanding our AI-powered data discovery tools, ensuring that Grabbers have every dataset they need to drive Grab’s success at their fingertips. The future of data discovery at Grab is brimming with possibilities, and the Hubble team is thrilled to be at the forefront of this exciting journey.

To our readers, we hope that our journey has inspired you to explore how you can leverage the power of AI to transform data discovery within your own organisations. The challenges you face may be unique, but the principles and strategies we have shared can serve as a foundation for your own data discovery revolution. By embracing innovation, focusing on user needs, and harnessing the potential of cutting-edge technologies, you too can unlock the full potential of your data and propel your organisation to new heights. The future of data-driven innovation is here, and we invite you to join us on this exhilarating journey.

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 700 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

High-risk vulnerabilities in common enterprise technologies

Post Syndicated from Rapid7 original https://blog.rapid7.com/2024/09/19/etr-high-risk-vulnerabilities-in-common-enterprise-technologies/

High-risk vulnerabilities in common enterprise technologies

Rapid7 is warning customers about several high-risk vulnerabilities in common enterprise technologies that are attractive potential attack targets for both state-sponsored and financially motivated adversaries. We are advising customers to prioritize remediation for these issues on an expedited basis wherever possible:

  • CVE-2024-41874: Critical remote code execution vulnerability in Adobe ColdFusion
  • CVE-2024-38812, CVE-2024-38813: Remote code execution and privilege escalation vulnerabilities (respectively) in Broadcom VMware vCenter Server and Cloud Foundation
  • CVE-2024-29847: Critical remote code execution (via deserialization) vulnerability in Ivanti Endpoint Manager (EPM)

Adobe ColdFusion CVE-2024-41874

On September 10, 2024, Adobe published a critical advisory for CVE-2024-41874, an unauthenticated remote code execution issue that occurs as a result of unsafe Web Distributed Data eXchange (“Wddx”) packet deserialization. Rapid7 MDR has previously observed exploitation that targets Wddx for remote code execution; we have also previously observed exploitation of multiple other ColdFusion CVEs.

Affected products and mitigation: Adobe ColdFusion 2023 (update 9 and earlier) and Adobe ColdFusion 2021 (update 15 and earlier) are vulnerable to CVE-2024-41874. The vulnerability is resolved in versions 10 and 16, respectively. For more information, see the vendor advisory.

Broadcom VMware vCenter Server CVEs

On September 17, 2024, Broadcom published an advisory on CVE-2024-38812, a critical heap overflow vulnerability affecting VMware vCenter Server. Successful exploitation of CVE-2024-38812 allows an attacker with network access to the vulnerable server to execute code remotely on the target system. CVE-2024-38813, a local privilege escalation vulnerability, was also reported by the same researchers, making this a full-chain exploit. We are not aware of exploitation in the wild as of September 19, 2024, but vCenter Server is a high-value attack target for ransomware and extortion groups.

Affected products and mitigation: Broadcom VMware vCenter Server 7.0 and 8.0 are vulnerable to CVE-2024-38812 and CVE-2024-38813. Fixes are available as indicated in the vendor advisory. Broadcom also has an FAQ available.

Ivanti Endpoint Manager CVE-2024-29847

On September 10, 2024, Ivanti published a security advisory on CVE-2024-29847, an unsafe deserialization vulnerability in Ivanti Endpoint Manager (EPM) solution. Successful exploitation allows unauthenticated attackers to execute code remotely on target systems. Vulnerability details and proof-of-concept exploit code are available.

Affected products and mitigation: Ivanti Endpoint Manager (EPM) 2022 SU5 (and earlier) and EPM 2024 are vulnerable to CVE-2024-29847. Customers using EPM 2022 can remediate this and other recent vulnerabilities by updating to 2022 SU 6. Per Ivanti’s security advisory, EPM 2024 customers can apply an available security patch while waiting for 2024 SU1, which is yet to be released. See Ivanti’s advisory for the latest information.

Rapid7 customers

InsightVM and Nexpose customers can assess their exposure to Adobe ColdFusion CVE-2024-41874 and Broadcom VMware vCenter Server CVE-2024-28812 and CVE-2024-38813 with vulnerability checks released previously. A vulnerability check for Ivanti EPM CVE-2024-29847 is in development and is expected to be available in tomorrow’s (Friday, September 20) content release.

AWS named as a Leader in the 2024 Gartner Magic Quadrant for Desktop as a Service (DaaS)

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/aws-named-as-a-leader-in-the-2024-gartner-magic-quadrant-for-desktop-as-a-service-daas/

The 2024 Gartner Magic Quadrant for DaaS (Desktop as a Service) positions AWS as a Leader for the first time. Last year we were recognized as a Challenger. We believe this is a result of our commitment to meet a wide range of customer needs by delivering a diverse portfolio of virtual desktop services with license portability (including Microsoft 365 Apps for Enterprise), our geographic strategy, and operational capabilities focused on cost optimization and automation. Also, our focus on easy-to-use interfaces for managing each aspect of our virtual desktop services means that our customers rarely need to make use of third-party tools.

You can access the complete 2024 Gartner Magic Quadrant for Desktop as a Service (DaaS) to learn more.

2024-Gartner-MQ-for-DaaS-Graph

AWS DaaS Offerings
Let’s take a quick look at our lineup of DaaS offerings (part of our End User Computing portfolio):

Amazon WorkSpaces Family – Originally launched in early 2014 and enhanced frequently ever since, Amazon WorkSpaces gives you a desktop computing environment running Microsoft Windows, Ubuntu, Amazon Linux, or Red Hat Enterprise Linux in the cloud. Designed to support remote & hybrid workers, knowledge workers, developer workstations, and learning environments, WorkSpaces is available in sixteen AWS Regions, in your choice of six bundle sizes, including the GPU-equipped Graphics G4dn bundle. WorkSpaces Personal gives each user a persistent desktop — perfect for developers, knowledge workers, and others who need to install apps and save files or data. If your users do not need persistent desktops (often the case for contact centers, training, virtual learning, and back office access) you can use WorkSpaces Pools to simplify management and reduce costs. WorkSpaces Core provides managed virtual desktop infrastructure that is designed to work with third-party VDI solutions such as those from Citrix, Leostream, Omnissa, and Workspot.

Amazon WorkSpaces clients are available for desktops and tablets, with web access (Amazon WorkSpaces Secure Browser) and the Amazon WorkSpaces Thin Client providing even more choices. If you have the appropriate Windows 10 or 11 desktop license from Microsoft, you can bring your own license to the cloud (also known as BYOL), where it will run on hardware that is dedicated to you.

You can read about the Amazon WorkSpaces Family and review the WorkSpaces Features to learn more about what WorkSpaces has to offer.

Amazon AppStream 2.0 – Launched in late 2016, Amazon AppStream gives you instant, streamed access to SaaS applications and desktop applications without writing code or refactoring the application. You can easily scale applications and make them available to users across the globe without the need to manage any infrastructure. A wide range of compute, memory, storage, GPU, and operating system options let you empower remote workers, while also taking advantage of auto-scaling to avoid overprovisioning. Amazon AppStream offers three fleet types: Always on (instant connections), On-Demand (2 minutes to launch), and Elastic (for unpredictable demand). Pricing varies by type, with per second and per hour granularity for Windows and Linux; read Amazon AppStream 2.0 Pricing to learn more.

— Jeff;

Gartner does not endorse any vendor, product or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.

GARTNER is a registered trademark and service mark of Gartner and Magic Quadrant is a registered trademark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and are used herein with permission. All rights reserved.

This graphic was published by Gartner, Inc. as part of a larger research document and should be evaluated in the context of the entire document. The Gartner document is available upon request from AWS.

[$] Best practices for error handling in kernel Rust

Post Syndicated from daroc original https://lwn.net/Articles/990489/

Dirk Behme led a session discussing the use of Rust’s question-mark operator in
the kernel at Kangrejos 2024. He was particularly concerned with the concept of
“silent” errors that don’t print any messages to the console.
Other attendees were less convinced that this was a problem, but his presentation
sparked a lot of discussion about whether the Rust-for-Linux project could
improve error handling in kernel Rust code.

FBI Shuts Down Chinese Botnet

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/09/fbi-shuts-down-chinese-botnet.html

The FBI has shut down a botnet run by Chinese hackers:

The botnet malware infected a number of different types of internet-connected devices around the world, including home routers, cameras, digital video recorders, and NAS drives. Those devices were used to help infiltrate sensitive networks related to universities, government agencies, telecommunications providers, and media organizations…. The botnet was launched in mid-2021, according to the FBI, and infected roughly 260,000 devices as of June 2024.

The operation to dismantle the botnet was coordinated by the FBI, the NSA, and the Cyber National Mission Force (CNMF), according to a press release dated Wednesday. The U.S. Department of Justice received a court order to take control of the botnet infrastructure by sending disabling commands to the malware on infected devices. The hackers tried to counterattack by hitting FBI infrastructure but were “ultimately unsuccessful,” according to the law enforcement agency.

AWS renews its GNS Portugal certification for classified information with 66 services

Post Syndicated from Daniel Fuertes original https://aws.amazon.com/blogs/security/aws-renews-its-gns-portugal-certification-for-classified-information-with-66-services/

Amazon Web Services (AWS) announces that it has successfully renewed the Portuguese GNS (Gabinete Nacional de Segurança, National Security Cabinet) certification in the AWS Regions and edge locations in the European Union. This accreditation confirms that AWS cloud infrastructure, security controls, and operational processes adhere to the stringent requirements set forth by the Portuguese government for handling classified information at the National Reservado level (equivalent to the NATO Restricted level).

The GNS certification is based on the NIST SP800-53 Rev. 5 and CSA CCM v4 frameworks. It demonstrates the AWS commitment to providing the most secure cloud services to public-sector customers, particularly those with the most demanding security and compliance needs. By achieving this certification, AWS has demonstrated its ability to safeguard classified data up to the Reservado (Restricted) level, in accordance with the Portuguese government’s rigorous security standards.

AWS was evaluated by an authorized and independent third-party auditor, Adyta Lda, and by the Portuguese GNS itself. With the GNS certification, AWS customers in Portugal, including public sector organizations and defense contractors, can now use the full extent of AWS cloud services to handle national restricted information. This enables these customers to take advantage of AWS scalability, reliability, and cost-effectiveness, while safeguarding data in alignment with GNS standards.

We’re happy to announce the addition of 40 services to the scope of our GNS certification, for a new total of 66 services in scope. To view the complete list of services included in the scope, see the AWS Services in Scope by Compliance Program – GNS National Restricted Certification page.

The Certificate of Compliance illustrating the compliance status of AWS is available on the GNS Certifications page and through AWS Artifact.

For more information about GNS, see the AWS Compliance page GNS National Restricted Certification.

If you have feedback about this post, submit comments in the Comments section below.
 

Daniel Fuertes
Daniel Fuertes

Daniel is a Security Audit Program Manager at AWS, based in Madrid, Spain. Daniel leads multiple security audits, attestations, and certification programs in Spain, Portugal, and other EMEA countries. Daniel has ten years of experience in security assurance and compliance, including previous experience as an auditor for the PCI DSS security framework. He also holds the CISSP, PCIP, and ISO 27001 Lead Auditor certifications.

[$] RPM 4.20 is coming

Post Syndicated from jzb original https://lwn.net/Articles/988927/

The RPM Package Manager (RPM) project is
nearing the release of RPM 4.20, the last major planned update for the RPM 4.x
series. It has few user-facing changes, but
several additions and enhancements for developers—as well as
some small incompatibilities that will likely require RPM packagers to
revise their spec
files
. 4.20 will be rolling out to many users soon, in
Fedora 41, which is scheduled for October. RPM 6.0 is
already in the works, with a new package format and opening the door
to enabling C++ use in the RPM codebase.

Help, I can’t see! A Primer for Attack Surface Management Blog Series

Post Syndicated from Jon Schipp original https://blog.rapid7.com/2024/09/19/help-i-cant-see-a-primer-for-attack-surface-management-blog-series/

Part 1: Overview of the Problem ASM Solves and a High-Level Description of ASM and Its Components

Help, I can’t see! A Primer for Attack Surface Management Blog Series

Welcome to the first installment of our multipart series, “Help! I Can’t See! A Primer for Attack Surface Management Blog Series.” In this series, we will explore the critical challenges and solutions associated with Attack Surface Management (ASM), a vital aspect of modern cybersecurity strategy. This initial blog, titled “Overview of the Problem ASM Solves and a High-Level Description of ASM and Its Components,” sets the stage by examining the growing difficulties organizations face in managing their digital environments and how ASM can help address these issues effectively.

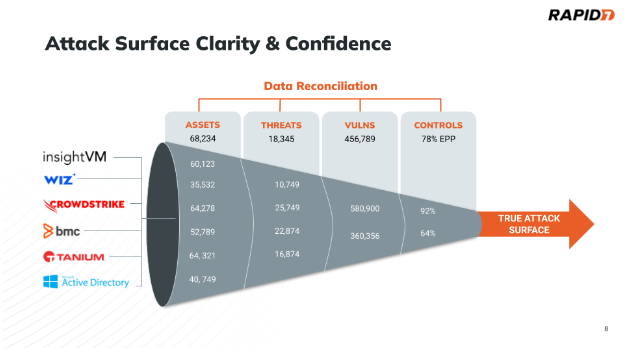
The fast paced evolution of digital infrastructure that is driving businesses forward (e.g. workstations, virtual machines, containers, edge) is also making it more difficult for organizations to keep track of and account for the cyber attack surface they’re responsible for protecting. Despite security teams continuing to invest exorbitant amounts of money on tools (VM, EDR, CNAPP, etc.) to both manage their digital environment and also secure it, the problem isn’t getting any better. In this 3-part blog series  we will help demystify the problems of security data silos and tool sprawl so you can answer pertinent questions like

  • How many assets and identities am I responsible for protecting?
  • How many assets and identities are lacking security controls like endpoint security or MFA?
  • What is my overall security posture?

When we look at the number and types of tools organizations spend money on to manage and secure their digital environment, we typically see things like vulnerability scanners, endpoint security, IdP, patching, IT asset management, Cloud Service Providers, and more.  Each of these tools and technologies tend to do a pretty good job at their core function but unintentionally contribute to a fractured ecosystem that provides organizations with contradictory information about their digital environment.

Help, I can’t see! A Primer for Attack Surface Management Blog Series

The age old problem: How many assets do I have?

Let’s look at a real-world example of this where an organization has solutions for Vulnerability Management (VM), Cloud Security Posture Management (CSPM), Endpoint Security (EDR/EPP), Active Directory (Directory Services) and IT Asset Management( ITAM).

Help, I can’t see! A Primer for Attack Surface Management Blog Series

None of these tools can agree on the number of assets in the environment. It’s practically  impossible to achieve 100% deployment of agent-based tools across your business (some types of assets cannot have agents!). It then becomes a real challenge to see across these tooling visibility gaps. The result is that we cannot answer the basic question of “How many assets am I responsible for protecting”.

This fact is compounded because if we can’t agree on the total number of assets, then we don’t know the number of controls in place, the number of vulnerabilities and exposures that exist, and the number of active threats in our environment. Teams that manage and secure organizations are relying upon incorrect information in an environment where prioritization and decision making needs to be based on high-fidelity information that incorporates IT, security, and business context to lead to the best outcomes.

To drill down on  these points, let’s pick on a few tools from the infographic for illustrative purposes. Wiz will only see assets in the cloud, Active Directory only sees assets (mostly Windows) tied to the Domain Controller, and traditional vulnerability scanners see across hybrid environments but tend to be mostly deployed on-premise. If you hone in on the numbers in the Asset column you will immediately notice that none of these tools agree on the number of assets in the environment. Lacking visibility and confidence in your attack surface is a big data problem, and deploying the latest shiny security tool is not going to fix it.

Ultimately, we have an industry created data problem that Rapid7 is not immune to. For a number of perfectly good reasons, we have created a fractured technology ecosystem that is preventing security teams from having the best data available to determine their cyber risk and enabling them to prioritize the most effective remediation and response.

We need to see across the gaps that truly matter; for that we need Attack Surface Management.

What is Attack Surface Management?

Attack Surface Management (ASM) is generally part of a wider Exposure Management program and  is a different way to think about cyber risk by focusing on addressing the digital parts of the business that are most vulnerable to attack. Taking an attack surface-based approach to your security program needs to consider a number of different elements including:

  • Discovery and inventory of all cyber assets in the organization, from the endpoint to the cloud
  • Internet-scanning to identify unknown exposures and map them to the existing asset inventory
  • High-fidelity visibility and insights into the IT, security, and business context of those assets
  • Relationship-mapping between the assets and the wider network and business infrastructure

ASM is a continuous process that is constantly assessing the state of the attack surface by uncovering new or updated assets, identifying the use of shadow IT in network or cloud use cases and prioritizing exposures based on their potential risk to the business. These elements of discovery and prioritization are foundational elements of a Continuous Threat Exposure Management (CTEM) initiative, where security teams are taking a more holistic approach to managing all types of exposures in their organizations.

A positive trend that we are currently seeing is that security teams are going back to basics and focusing on cyber asset management to first discover and understand the assets they’re responsible for protecting, along with their business function.

They gain visibility into the assets through a combination of external scanning to identify internet-facing assets which are potentially higher risk, this is known as External Attack Surface Management (EASM). A  complementary approach to cyber asset discovery  that provides greater insights into the whole cyber estate uses API-based integrations into existing IT management and security tools to ingest asset data; this is known as Cyber Asset Attack Surface Management (CAASM). Together, they provide organizations with the asset visibility they need to drive security decisions.

Put simply, you cannot secure what you can’t see. Managing the attack surface requires asset discovery and visibility, combined with rich context from all tools in the environment.

Attack Surface Management vs. Asset Inventory

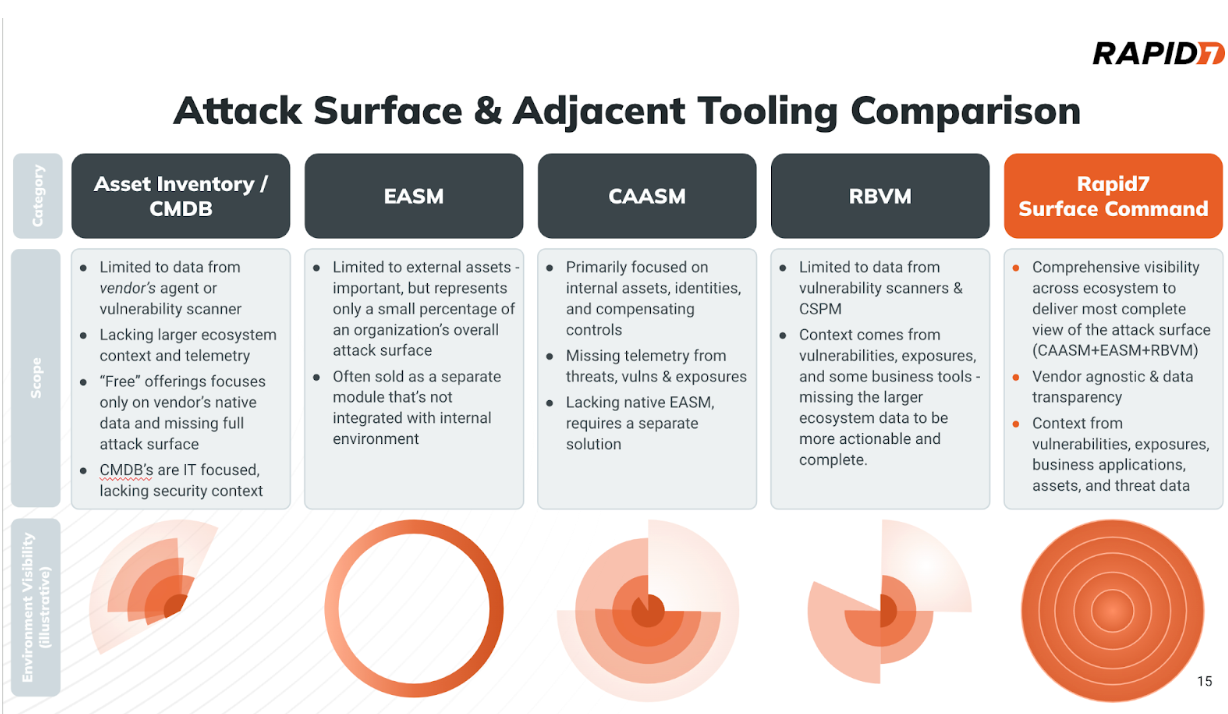
There is a common confusion with customers today that they already have elements of an ASM strategy with their current approach to asset inventory. This is typically based on an asset inventory system that IT is using for asset lifecycle management. A traditional asset inventory’s view of the environment is almost entirely based on what it is able to discover on its own, and with an IT focus. These are often agent-based,  with limited integrations, so they are not able to take advantage of an organization’s wide range of tools, which impairs their value.

Many asset inventories today can only discover assets where they have a deployed agent, such as an endpoint agent or being tied to the domain controller. While these technologies are effective at making policy and configuration changes on their fleet of endpoints, they do not have a data aggregation and correlation engine that sees beyond the specific agent. Additionally, they have limited security insights and context, and are only able to provide a partial view of the attack surface, assuming that no agent has 100% coverage.

This is not the reality in most organizations, and it’s why one should not confuse Asset Inventories with Attack Surface Management, the latter being a much more effective approach to surfacing the best asset and security telemetry across your ecosystem. An Attack Surface Management solution will ingest data from an IT Asset Inventory or Management tool as one of many data sources to collate.

The next blog in this series will look at the different components of an ASM program, and how they can be leveraged to improve security hygiene and reduce cyber risk.

Help, I can’t see! A Primer for Attack Surface Management Blog Series

Announcing Support for IPv6

Post Syndicated from Anthony Hoppe original https://www.backblaze.com/blog/announcing-support-for-ipv6/

An illustration of network connections on a gradient background.

If your systems are IPv6-enabled or enabling IPv6 is on your roadmap, good news—starting yesterday and continuing over the course of the next few weeks, Backblaze will be “flipping the switch” and turning on IPv6 for our S3 Compatible API. While our IPv6 deployment isn’t completely done yet (we’re phasing the roll out through our environment), we thought we’d share some of the decisions we made that affect performance and functionality.   

Today, I’ll talk a little bit more about our choices along the way, and answer some questions that might come up about how we’re supporting the protocol (jump to the FAQ for that).

Hi, I’m Anthony

Since this is the first time you’re hearing from me, I thought I should introduce myself. I’m a senior network engineer here at Backblaze. The Network Engineering group is responsible for ensuring the reliability, capacity, and security of network traffic, and that includes our IPv6 deployment.

What is IPv6 and why did we enable it?

Internet protocol version 6 (IPv6) is replacing internet protocol version 4 (IPv4) as the standard for IP addresses. Most of the internet uses IPv4, and this protocol has been reliable and resilient for over 20 years. However, IPv4 has limitations that might cause problems as the internet expands—namely, there aren’t enough IPv4 addresses to go around. 

Demand for IPv6 is continuing to increase exponentially. A major factor in this is the combination of the continually growing population and the number of connected devices a given person carries. One study from 2020 suggests the average number of connected devices per person globally was 2.4 in 2018, and forecasted to be 3.6 in 2023. Specifically for North America, the study suggests 8.2 connected devices in 2018 and a whopping 13.4 in 2023! Every device connected to the internet needs an IP address, and the finite address space of IPv4 it is simply no longer sufficient. The key to IPv6 enhancement is the expansion of the IP address space from 32 bits to 128 bits, enabling virtually unlimited, unique IP addresses.

Support for IPv6 means our customers can reach our services in the most efficient and secure way possible.

Why should you care about us deploying IPv6?

We’ve learned some things over the years, so we approached our IPv6 deployment a little differently than our IPv4 deployment. If you’re a customer or potential customer, here’s what that means for you: 

  1. No action needed on your part: Unlike some of the traditional cloud providers, we chose to use the same endpoint URL and let the client choose whether or not to use IPv6. This allows for any systems already IPv6 enabled to benefit immediately. In fact, if your systems are IPv6 enabled and you are a B2 customer using the S3 compatible API, you might already be connecting to us over IPv6 now.
  2. Our deployment is better set up to scale: Because of the way we decided to assign virtual IPs (VIPs) to our API endpoints, we have more flexibility to distribute ingress traffic and the ability to add VIPs as we need to in the future.
  3. Improved network performance and simpler network management: With IPv6, we simplified IP assignments and reduced the need for customers to use Network Address Translation (NAT). NAT adds processing overhead to network traffic as it translates IP addresses, which can lead to latency issues, especially with high-volume data transfer. The less traffic you have to NAT, the better. On our end, there is no NAT with customer data flows regardless of IPv4 vs IPv6. We also made the decision to route traffic before using network switches, this helps with reducing IPv6 multicast “noise” and generally helps keep the “wire” cleaner.

And here’s how we got it all done.

If a VIP could only talk

First, a little background: Backblaze offers two APIs—the Backblaze S3 Compatible API and the Backblaze B2 Native API. You can learn more about our APIs here in our documentation, but a couple differences are important to note when it comes to our IPv6 deployment:

  • Backblaze B2 Native API: Uploads are sent directly to a Backblaze Vault. As part of the process of uploading a file, the client is provided an “upload URL”, which is a direct URL to an assigned member of the storage Vault. The data transfer is direct from the client to the storage Vault. Only downloads are served by the API server pool. Load balancers mainly handle distributing API calls.
  • S3 Compatible API: Uploads flow through load balancers and the API server pool. Our API server pool then distributes the data to the assigned Vault. Downloads are served by our API server pool just like Backblaze B2 Native API.

These functionality differences play a role in how we are able to perform traffic engineering.  We assign VIPs to our API endpoints, for example, s3.us-west-004.backblazeb2.com, or api004.backblazeb2.com. These VIPs are owned by our load balancers and API servers (for Direct Server Return). With the Backblaze B2 Native API, we really only need two VIPs per cluster: one for uploads and one for downloads. The upload URL that B2 Native provides to the client naturally distributes the flow across our IP space. With the S3 Compatible API, since uploads and downloads are handled by the same flow, we only needed one VIP…or so we thought.

Assigning a single VIP to the S3 Compatible API has been fine for a long time. However, as we’ve grown, and usage of the S3 Compatible API has grown, we discovered that a single S3 Compatible API VIP makes traffic engineering ingress flows challenging. When a large percentage of our S3 Compatible API ingress traffic happens to come from providers that prefer getting to us via a single path, having all that traffic destined to a single IP means we have no ability to steer (i.e.traffic engineer) portions of the traffic.

Starting at the beginning of this year, we’ve grown the number of API VIPs in our datacenters with the highest amount of S3 Compatible API traffic from a single IP, to four IPs in four different network prefixes (also known as subnets). This allows us to steer portions of S3 Compatible API traffic. This also helps distribute flows so that providers that have equal cost paths to us can be better utilized.

Lesson learned: With IPv6, we standardized on four IPv6 VIPs in four different prefixes with plans to grow if/when needed.

Route when you can, switch only when you need to

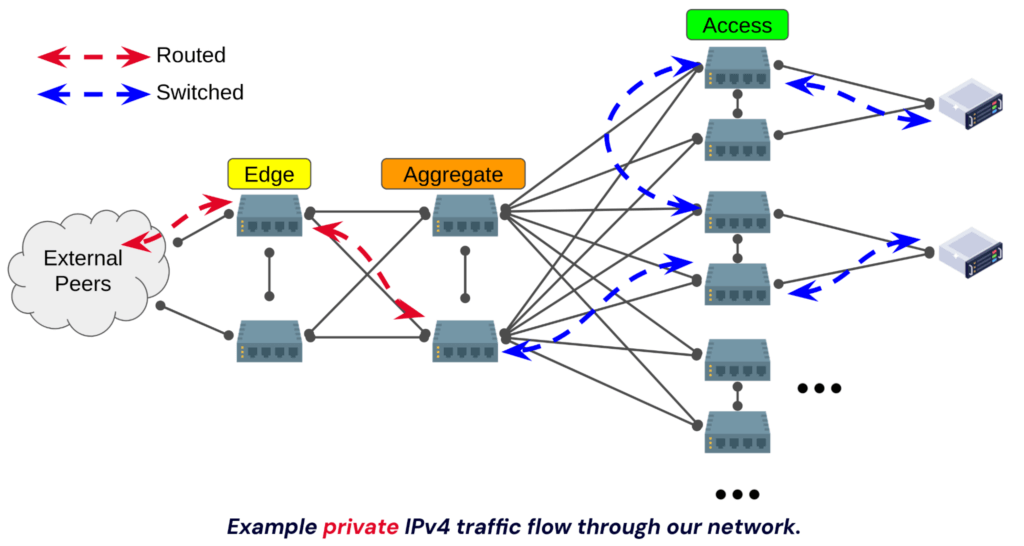
Backblaze datacenter networks are architected using a typical “three tier” approach. We have an edge layer, an aggregation layer (also known as a spine), and an access layer (also known as a leaf).

A diagram of a three-tier network design.

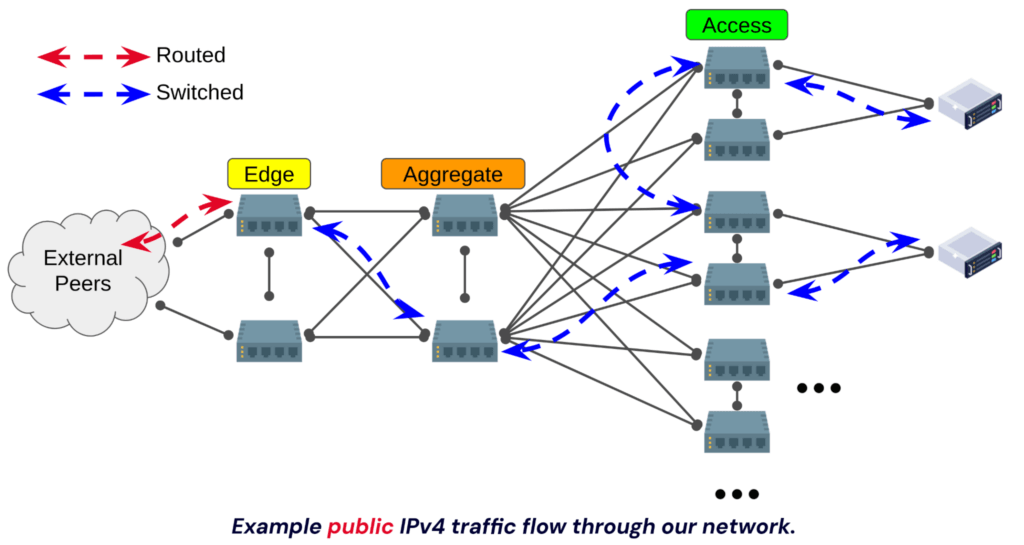
With IPv4, we have two IP “classes”. We have a private network (RFC 1918) and a public network. Every machine is assigned an IPv4 address on the private network, and only machines that need to directly interface with the outside world are assigned public IPv4 addresses. These two networks each reside within their own VLAN, and host networking is configured to tag traffic as necessary.

Given the tiered design of our network, different layers handle these VLANs. The aggregation layer acts as the router for the private network, and the edge layer acts as the router for the public network. From there, IPv4 traffic is switched, and thus we simply have two large (i.e. flat) VLANs for IPv4.

A diagram showing an example of how private IPv6 traffic travels through a network.
A diagram showing an example of how public IPv6 traffic travels through a network.

This has worked well (and still works just fine). A pair of VLANs that we can switch to anywhere in the datacenter keeps things simple. Hosts can reside anywhere within the datacenter and IPs can be assigned from the same pools. However, with IPv4 traffic being switched datacenter wide, the flat broadcast domain (thus the level of background broadcast noise) increases over time as the environment grows. In our largest (IP-space wise) datacenter we’ve needed to increase hosts’ arp cache size. With IPv6, we wanted to improve this.

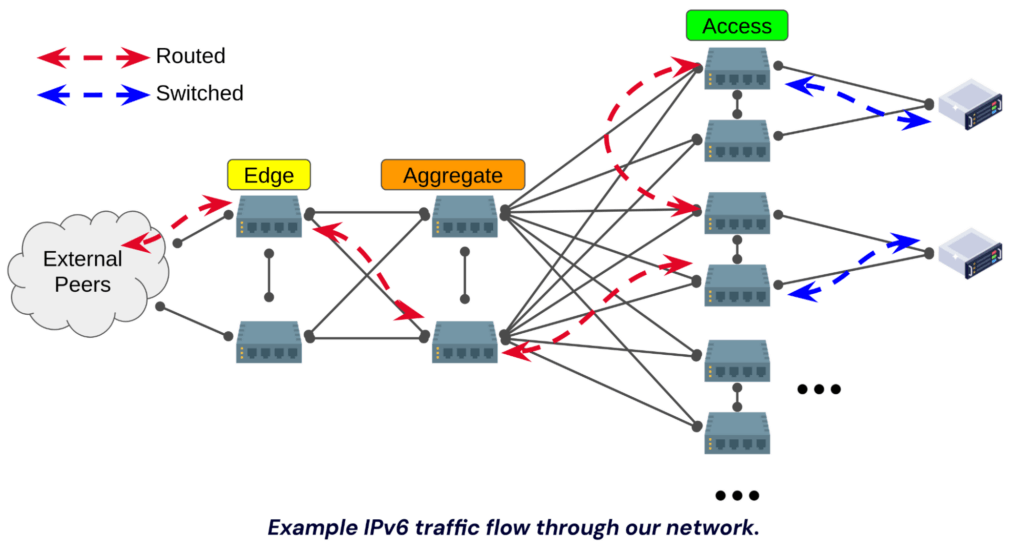
The first decision we made was to eliminate the concept of public vs private address space with IPv6. Every host gets an address and all addresses are public (if the role requires). Existing firewalls and switch ACLs already permit/deny traffic as appropriate (which is also the same for our IPv4 networks).

Not only does this simplify IP assignments, it also reduces the need for Network Address Translation (NAT). We have many hosts that are not public facing, but do need to communicate with the outside world for various reasons. As we are able to move more and more communication with external services to IPv6, this reduces the load on resources we’ve deployed simply to handle NAT.

The second decision that we made was to route all the way down to the access switch layer.  Each access switch is assigned a /64 and hosts connected to a given switch are assigned an IPv6 address from a portion of this block.

A diagram showing an example of how IPv6 traffic travels through the Backblaze network.

This helps with reducing IPv6 multicast “noise” and generally helps keep the “wire” cleaner.  It does make host deployments a little more complicated as in order to assign a given host an IPv6 address from the correct network, one needs to be aware of the switch the host is connected to. Also, if data center staff need to move hosts around for power balancing or consolidation, the IPv6 address will need to be changed if the new location results in the host connecting to a different switch. 

Lesson learned: Even with the added complexity, the route when you can, switch only when you need to mantra works well for our environment.

What’s next?

We still have more work ahead. We are currently investigating ways to support the Backblaze B2 Native API with IPv6 as well as Backblaze Computer Backup. Stay tuned for more on that front.

FAQs

What’s the difference between IPv4 and IPv6?

The key difference between the versions of the protocol is that IPv6 has significantly more address space. The IPv6 address notation is eight groups of four hexadecimal digits with the groups separated by colons, for example 2001:db8:1f70:999:de8:7648:3a49:6e8, although there are methods to abbreviate this notation. For comparison, the IPv4 notation is four groups of decimal digits with the groups separated by dots, for example 198.51.100.1.

The expanded addressing capacity of IPv6 will enable the trillions of new internet addresses needed to support connectivity for a huge range of new devices such as phones, household appliances, and vehicles.

How can I use IPv6 with B2 Cloud Storage?

Currently, only the Backblaze S3-compatible API supports IPv6. To use IPv6 addresses with B2 Cloud Storage and the S3-compatible API, you do not need to make any changes.

Will IPv4 addresses still work?

Yes, IPv4 addresses will continue to be supported for both the B2 Native API and the S3-compatible API for the time being. We do not have any explicit plans for sunsetting IPv4 at this time.

What will happen if I continue to use IPv4?

Nothing. IPv4 will continue to be supported at this time.

Is IPv6 better/more secure than IPv4?

It is not more secure. Customers who reach us via IPv4 or IPv6 will have connections that are equally secure. Our APIs use the same strong TLS encryption regardless if IPv4 or IPv6 is used. Some customers may see a performance improvement if IPv6 allows them to avoid network address translation (NAT).

Is there an additional cost to use IPv6?

No.

I’m using Backblaze Computer Backup. Do I need to make any changes?

No. IPv6 is only relevant for Backblaze B2 Cloud Storage. You don’t need to make any changes to your Backblaze Computer Backup account.

The post Announcing Support for IPv6 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Security updates for Thursday

Post Syndicated from jake original https://lwn.net/Articles/990877/

Security updates have been issued by Debian (expat and tinyproxy), Fedora (frr, microcode_ctl, python3.10, python3.12, python3.6, and ruby), Oracle (expat, fence-agents, firefox, ghostscript, java-1.8.0-openjdk, kernel, and thunderbird), Red Hat (firefox, openssl, ruby:3.3, and thunderbird), SUSE (clamav, ffmpeg-4, kernel, libmfx, python3, python312, runc, ucode-intel, and wireshark), and Ubuntu (apache2, git, linux, linux-aws, linux-aws-5.15, linux-azure, linux-azure-5.15, linux-gcp, linux-gcp-5.15, linux-gke, linux-gkeop, linux-gkeop-5.15, linux-hwe-5.15, linux-ibm, linux-intel-iotg, linux-intel-iotg-5.15, linux-kvm, linux-nvidia, linux-oracle, linux-raspi, linux, linux-aws, linux-aws-5.4, linux-azure, linux-azure-5.4, linux-bluefield, linux-gcp, linux-gcp-5.4, linux-gkeop, linux-hwe-5.4, linux-ibm, linux-ibm-5.4, linux-kvm, linux-oracle, linux-oracle-5.4, linux-xilinx-zynqmp, and linux, linux-aws, linux-gcp, linux-gke, linux-ibm, linux-lowlatency, linux-lowlatency-hwe-6.8, linux-nvidia, linux-nvidia-6.8, linux-nvidia-lowlatency, linux-oem-6.8, linux-oracle).

The collective thoughts of the interwebz