Tag Archives: announcements

Time-based snapshot copy for Amazon EBS

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/time-based-snapshot-copy-for-amazon-ebs/

You can now specify a desired completion duration (15 minutes to 48 hours) when you copy an Amazon Elastic Block Store (Amazon EBS) snapshot within or between AWS Regions and/or accounts. This will help you to meet time-based compliance and business requirements for critical workloads. For example:

Testing – Distribute fresh data on a timely basis as part of your Test Data Management (TDM) plan.

Development – Provide your developers with updated snapshot data on a regular and frequent basis.

Disaster Recovery – Ensure that critical snapshots are copied in order to meet a Recovery Point Objective (RPO).

Regardless of your use case, this new feature gives you consistent and predictable copies. This does not affect the performance or reliability of standard copies—you can choose the option and timing that works best for each situation.

Creating a Time-Based Snapshot Copy
I can create time-based snapshot copies from the AWS Management Console, CLI (copy-snapshot), or API (CopySnapshot). While working on this post I created two EBS volumes (100 GiB and 1 TiB), filled each one with files, and created snapshots:

To create a time-based snapshot, I select the source as usual and choose Copy snapshot from the Action menu. I enter a description for the copy, choose the us-east-1 AWS Region as the destination, select Enable time-based copy, and (because this is a time-critical snapshot), enter a 15 minute Completion duration:

When I click Copy snapshot, the request will be accepted (and the copy will become Pending) only if my account’s throughput quotas are not already exceeded due to the throughput consumed by other active copies that I am making to the destination region. If the account level throughput quota is already exceeded, the console will display an error.

I can click Launch copy duration calculator to get a better idea of the minimum achievable copy duration for the snapshot. I open the calculator, enter my account’s throughput limit, and choose an evaluation period:

The calculator then uses historical data collected over the course of previous snapshot copies to tell me the minimum achievable completion duration. In this example I copied 1,800,000 MiB in the last 24 hours; with time-based copy and my current account throughput quota of 2000 MiB/second I can copy this much data in 15 minutes.

While the copy is in progress, I can monitor progress using the console or by calling DescribeSnapshots and examining the progress field of the result. I can also use the following Amazon EventBridge events to take actions (if the copy operation crosses regions, the event is sent in the destination region):

copySnapshot – Sent after the copy operation completes.

copyMissedCompletionDuration – Sent if the copy is still pending when the deadline has passed.

Things to Know
And that’s just about all there is to it! Here’s what you need to know about time-based snapshot copies:

CloudWatch Metrics – The SnapshotCopyBytesTransferred metric is emitted in the destination region, and reflect the amount of data transferred between the source and destination region in bytes.

Duration – The duration can range from 15 minutes to 48 hours in 15 minute increments, and is specified on a per-copy basis.

Concurrency – If a snapshot is being copied and I initiate a second copy of the same snapshot to the same destination, the duration for the second one starts when the first one is completed.

Throughput – There is a default per-account limit of 2000 MiB/second between each source and destination pair. If you need additional throughput in order to meet your RPO you can request an increase via the AWS Support Center. Maximum per-snapshot throughput is 500 MiB/second and cannot be increased.

Pricing – Refer to the Amazon EBS Pricing page for complete pricing information.

Regions – Time-based snapshot copies are available in all AWS Regions.

— Jeff;

Announcing future-dated Amazon EC2 On-Demand Capacity Reservations

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/announcing-future-dated-amazon-ec2-on-demand-capacity-reservations/

Customers use Amazon Elastic Compute Cloud (Amazon EC2) to run every type of workload imaginable, including web hosting, big data processing, high-performance computing (HPC), virtual desktops, live event streaming, and databases. Some of these workloads are so critical that customers asked for the ability to reserve capacity for them.

To help customers flexibly reserve capacity, we launched EC2 On-Demand Capacity Reservations (ODCRs) in 2018. Since then, customers have used capacity reservations (CRs) to run critical applications like hosting consumer websites, streaming lives sporting events and processing financial transactions.

Today, we’re announcing the ability to get capacity for future workloads using CRs. Many customers have future events such as product launches, large migrations, or end-of-year sales events like Cyber Monday or Diwali. These events are critical, and customers want to ensure they have the capacity when and where they need it.

While CRs helped customers reserve capacity for these events, they were only available just-in-time. So customers either needed to provision the capacity ahead of time and pay for it or plan with precision to provision CRs just-in-time at the start of the event.

Now you can plan and schedule your CRs up to 120 days in advance. To get started you specify the capacity you need, the start date, delivery preference, and the minimum duration you commit to use the capacity reservation. There are no upfront charges to schedule a capacity reservation. After Amazon EC2 evaluates and approves the request, it will activate the reservation on the start date, and customers can use it to immediately launch instances.

Getting started with future-dated capacity reservations
To reserve your future-dated capacity, choose Capacity Reservations on the Amazon EC2 console and select Create On-Demand Capacity Reservation, and choose Get started.

To create a capacity reservation, specify the instance type, platform, Availability Zone, platform, tenancy, and number of instances you are requesting.

future-dated-2a

In the Capacity Reservation details section, choose At a future date in the Capacity Reservation starts option and choose your start date and commitment duration.

future-dated-1a

You can also choose to end the capacity reservation at a specific time or manually. If you select Manually, the reservation has no end date. It will remain active in your account and continue to be billed until you manually cancel it. To reserve this capacity, choose Create.

future-dated-4

After you create your capacity request, it appears in the dashboard with an Assessing status. During this state, AWS systems will work to determine if your request is supportable which is usually done within 5 days. Once the systems determine the request is supportable, the status will be changed to Scheduled. In rare cases, your request may be unsupported.

On your scheduled date, the capacity reservation will change to an Active state, the total instance count will be increased to the amount requested, and you can immediately launch instances.

After activation, you must hold the reservation for at least the commitment duration. After the commitment duration elapses, you can continue to hold and use the reservation if you’d like or cancel it if no longer needed.

Things to know
Here are some things that you should know about the future-dated CRs:

  • Evaluation – Amazon EC2 considers multiple factors when evaluating your request. Along with forecasted supply, Amazon EC2 considers how long you plan to hold the capacity, how early you create the Capacity Reservation relative to your start date, and the size of your request. To improve the ability of Amazon EC2 to support your request, create your reservation at least 56 days (8 weeks) before the start date. You need to submit a request for at least 100 vCPUs for only C, M, R, T, I instance types. The recommended minimum commitment for most requests will be 14 days.
  • Notification – We recommend monitoring the status of your request through the console or Amazon EventBridge You can use these notifications to trigger automation or send an email or text update. To learn more, visit Send an email when events happen using Amazon EventBridge in the Amazon EventBridge User Guide.
  • Pricing – Future dated capacity reservations are billed just like regular CRs. It is charged at the equivalent On-Demand rate whether you run instances in reserved capacity or not. For example, if you create a future dated CR for 20 instances and run 15 instances, you will be charged for 15 active instances and for 5 unused instances in the reservation including the minimum duration. Savings Plans apply to both unused reservations and instances running on the reservation. To learn more, visit Capacity Reservation pricing and billing in the Amazon EC2 User Guide.

Now available
Future dated EC2 Capacity Reservations are now available today in all AWS Regions where Amazon EC2 Capacity Reservations are available.

Give Amazon EC2 Capacity Reservations a try in the Amazon EC2 console. To learn more, visit On-Demand Capacity Reservations in the Amazon EC2 User Guide and send feedback to AWS re:Post for Amazon EC2 or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: 197 new launches, AI training partnership with Anthropic, and join AWS re:Invent virtually (Nov 25, 2024)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-197-new-launches-ai-training-partnership-with-anthropic-and-join-aws-reinvent-virtually-nov-25-2024/

Last week, I saw an astonishing 197 new service launches from AWS. This means we are getting closer to AWS re:Invent 2024! Our News Blog team is also finalizing blog posts for re:Invent to introduce some awesome launches from service teams for your reading pleasure.

The most interesting news is that we’re expanding our strategic collaboration with Anthropic as our primary training partner for development of our AWS Trainium chips. This is in addition to being their primary cloud provider for deploying Anthropic’s Claude models in Amazon Bedrock. We’ll keep pushing the boundaries of what customers can achieve with generarive AI technologies with these kinds of collaborations.

Last week’s launches
Here are some AWS bundled feature launches:

Amazon Aurora – Amazon Aurora Serverless v2 now supports scaling to 0 Aurora Capacity Units (ACUs). With 0 ACUs, you can now save cost during periods of database inactivity. Instead of scaling down to 0.5 ACUs, the database can now scale down to 0 ACUs. Amazon Aurora is now compatible with MySQL 8.0.39 and PostgreSQL 17.0 in the Amazon RDS Database preview environment.

Amazon Bedrock – You can quickly build and execute complex generative AI workflows without writing code with the general availability of Amazon Bedrock Flows (previously known as Prompt Flows). Amazon Bedrock Knowledge Bases now supports binary vector embeddings for building Retrieval Augmented Generation (RAG) applications. Amazon Bedrock also introduce a preview launch of Prompt Optimization to rewrite prompts for higher quality responses from foundational models (FMs). You can use AWS Amplify AI kit to easily leverage your data to get customized responses from Bedrock AI models to build web apps with AI capabilities such as chat, conversational search, and summarization.

Amazon CloudFront – You can use gRPC applications in Amazon CloudFront that allows bidirectional communication between a client and a server over HTTP/2 connections. Amazon CloudFront introduces Virtual Private Cloud (VPC) origins to deliver content from applications hosted in VPC private subnets, and Anycast Static IPs to provide you with a dedicated list of IP addresses for connecting to all CloudFront edge locations worldwide. You can also conditionally change or update origin servers on each request with origin modification within CloudFront Functions, and use new log configuration and delivery options.

Amazon CloudWatch – You can use field indexes and log transformation to improve log analytics at scale in the CloudWatch Logs. You can also use enhanced search and analytics experience and runtime metrics support with CloudWatch Application Signals, and percentile aggregation and simplified events-based troubleshooting directly from the web vitals anomaly in CloudWatch Real User Monitoring (RUM).

Amazon Cognito – You can secure user access to your applications with passwordless authentication, including sign-in with passkeys, email, and text message. Amazon Cognito introduces Managed Login, hosted sign-in and sign-up experience that customers can personalize to align with their company or application branding. Cognito launches new user pool feature tiers: Essentials and Plus as well as a new developer-focused console experience. To learn more, visit Donnie’s blog post.

Amazon Connect – You can use new customer profiles and outbound campaigns to help you proactively address customer needs before they become potential issues. Amazon Connect Contact Lens now supports creating custom dashboards, as well as adding or removing widgets from existing dashboards. With new Amazon Connect Email, you can receive and respond to emails sent by customers to business addresses or submitted via web forms on your website or mobile app.

Amazon EC2 – You can shift the launches of EC2 instances in an Auto Scaling Group (ASG) away from an impaired Availability Zone (AZ) to quickly recover your unhealthy application in another AZ with Amazon Application Recovery Controller (ARC) zonal shift and zonal autoshift. Application Load Balancer (ALB) now supports HTTP request and response header modification giving you greater controls to manage your application’s traffic and security posture without having to alter your application code.

AWS End User Messaging (aka Amazon Pinpoint) – You can now track feedback for messages sent through the SMS and MMS channel, explicitly block or allow messages to individual phone numbers overriding your country rule settings, and cost allocation tags for SMS resources to track spend for each tag associated with a resource. AWS End User Messaging also now support integration with Amazon EventBridge.

AWS Lambda – You can use Lambda SnapStart for Python and .NET functions to deliver as low as sub-second startup performance. AWS Lambda now supports Amazon S3 as a failed-event destination for asynchronous invocations and Amazon CloudWatch Application Signals to easily monitor the health and performance of serverless applications built using Lambda. You can also use a new Node.js 22 runtime and Provisioned Mode for event source mappings (ESMs) that subscribe to Apache Kafka event sources.

Amazon OpenSearch Service – You can scale a single cluster to 1000 data nodes (1000 hot nodes and/or 750 warm nodes) to manage 25 petabytes of data. Amazon OpenSearch Service introduces Custom Plugins, a new plugin management option to extend the search and analysis functions in OpenSearch.

Amazon Q Business – You can use tabular search to extract answers from tables embedded in documents ingested in Q Business. You can drag and drop files to upload and reuse any recently uploaded files in new conversations without uploading the files again. Amazon Q Business now supports integrations to Smartsheet in general, and Asana, Google Calendar in preview to automatically sync your index with your selected data sources. You can also use Q Business browser extensions for Google Chrome, Mozilla Firefox, and Microsoft Edge.

Amazon Q Developer – You can ask questions directly related to the AWS Management Console page you’re viewing, eliminating the need to specify the service or resource in your query. You can also use customizable chat responses generated by Q Developer in the IDE to securely connect Q Developer to your private codebases to receive more precise chat responses. Finally, you can use voice input and output capabilities in the AWS Console Mobile App along conversational prompts to list resources in your AWS account.

Amazon QuickSight – You can use Layer Map to visualize custom geographic boundaries, such as sales territories, or user-defined regions, and Image Component to upload your images directly for a variety of use cases, such as adding company logos. Amazon QuickSight also provides the ability to import visuals from an existing dashboard or analysis into your current analysis and Highcharts visuals to create custom visualizations using the Highcharts Core library in preview.

Amazon Redshift – You can ingest data from a wider range of streaming sources from Confluent Managed Cloud and self-managed Apache Kafka clusters on Amazon EC2 instances. You can also use enhanced security defaults which helps you adhere to best practices in data security and reduce the risk of potential misconfigurations.

AWS System Manager – You can use a new and improved version of AWS Systems Manager that brings a highly requested cross-account, and cross-Region experience for managing nodes at scale. AWS Systems Manager now supports instances running Windows Server 2025, Ubuntu Server 24.04, and Ubuntu Server 24.10.

Amazon S3 – You can configure S3 Lifecycle rules for S3 Express One Zone to expire objects on your behalf and append data to objects in S3 Express One Zone. You can also use Amazon S3 Express One Zone as a high performance read cache with Mountpoint for Amazon S3. Amazon S3 Connector for PyTorch now supports Distributed Checkpoint (DCP), improving the time to write checkpoints to Amazon S3.

Amazon VPC – You can use Block Public Access (BPA) for VPC, a new centralized declarative control that enables network and security administrators to authoritatively block Internet traffic for their VPCs. Amazon VPC Lattice now provides native integration with Amazon ECS, easily to deploy, manage, and scale containerized applications.

There’s a lot more launch news that I haven’t covered here. See AWS What’s New for more details.

See you virtually in AWS re:Invent
AWS re:Invent 2023Next week we’ll hear the latest news from AWS, learn from experts, and connect with the global cloud community in Las Vegas. If you come, check out the agenda, session catalog, and attendee guides before your departure.

If you’re not able to attend re:Invent in person, we’re offering the option to livestream our Keynotes and Innovation Talks. With the registration for online pass, you will have access to on-demand keynote, Innovation Talks, and selected breakout sessions after the event. You can also register with AWS Builder ID, a personal account that enables one-click event registration and provides access to many AWS tools and services.

Please stay tuned in the next week!

– Channy

Introducing a new experience for AWS Systems Manager

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/introducing-a-new-experience-for-aws-system-manager/

Today, I’m excited to introduce a new and improved version of AWS Systems Manager that brings a highly requested cross-account, and cross-Region experience for managing nodes at scale.

The new System Manager experience provides centralized visibility of all your managed nodes which include various infrastructure types, such as Amazon Elastic Compute Cloud (EC2) instances, containers, virtual machines on other cloud providers, on-premise servers, and edge Internet of Things (IoT) devices. They are referred to as “managed nodes” when they have the Systems Manager Agent (SSM Agent) installed and are connected to Systems Manager.

If an SSM Agent stops working on a node for whatever reason, then Systems Manager loses connection to it and that node is then referred to as an “unmanaged node.” With the new update, Systems Manager can also help you to easily discover and troubleshoot unmanaged nodes. You can run and even schedule an automated diagnosis that provides you with recommended runbooks that you can execute to fix any issues and reestablish connection so they become managed nodes again.

Systems Manager is also now integrated with Amazon Q Developer, the most capable generative AI–powered assistant for software development. You can ask questions about your managed nodes to Amazon Q Developer using natural language and it will provide you with rapid insights plus links straight to Systems Manager where you can perform actions or continue to explore further.

With this release, you can also use AWS Organizations, to allow a delegated administrator to centrally manage nodes across the organization thanks to the new integration with Systems Manager.

the new systems manager experience

Let’s examine a quick example that helps to demonstrate some of these new capabilities.

Imagine a scenario where you are a cloud platform engineer leading a migration plan aiming to replace all nodes running Windows Server 2016 Datacenter in the organization. Let’s use the new Systems Manager experience to quickly gather information about all the nodes that needs to be included in our plan.

Step 1 – Asking Amazon Q Developer
The easiest starting point is using Amazon Q Developer to ask what you want to find using natural language. Using the AWS Console, I open the Amazon Q chatbot and type Find all of my managed nodes running Microsoft Windows Server 2016 Datacenter in my organization.

Amazon Q quickly comes back with an answer: it tells us that there are ten nodes that fit the criteria and provides a list with an overview of each one.

There is also a link that redirects to the new Explore nodes page in System Manager where we can learn more information. Let’s follow it.

Step 2 – Reviewing our infrastructure
The Explore nodes page provides a comprehensive overview of all managed nodes across your organization, with options to group and filter results for quick access. In this case, we can see that the results are already filtered by Operating system name providing us with a list of all the nodes that are running Microsoft Windows Server 2016 Datacenter.

This is a great start! We could just finish here by downloading the report and add those nodes to our migration plan, however, this page only shows you information about your managed nodes. Could it be that there are unmanaged nodes that need to included in our plan? Let’s find out.

Step 3 – Handling unmanaged nodes
Open the menu, and navigate to the Review node insights page. Here you can see a dashboard with widgets that provide insightful interactive charts that you can use to drill down and discover more information about your nodes or even take actions. For example, the Managed node types pie chart shows the types of managed nodes we have whereas the SSM Agent versions graph provides us with an overview of all the different versions of SSM Agent running on them. You can also customize this view by adding and replacing widgets.

We want to investigate any unmanaged nodes to make sure we don’t miss any that may need to be added to our migration plan. The Node summary widget clearly shows that there are two unmanaged nodes. This could mean that these nodes don’t have the SSM Agent installed in which case we will need to investigate them manually. However, it could also just mean there are issues with the SSM agent permissions or network connectivity preventing Systems Manager from managing these nodes and treating them like any other managed node. The new Systems Manager experience allows you easily troubleshoot and remediate SSM Agents issues so let’s attempt to do this now.

Start by selecting the piece of the chart displaying our unmanaged nodes. This pops up an option to initiate a comprehensive diagnosis of all our unmanaged nodes with only one click. Let’s run this.

The diagnosis reviews key configurations such as missing virtual private cloud (VPC) endpoints, misconfigured VPC DNS settings, and misconfigured instance security groups that may be preventing the SSM Agent from connecting to Systems Manager. After the scanning is complete, we can see that it displays two Misconfigured VPC endpoint findings. It also gives you a link that you can use to open a side panel containing a recommended runbook that you can execute to solve the issues as well as links to relevant documentation.

Choosing to execute the recommended runbook presents you with a detailed preview of the changes which include a thorough overview of the actions it’s going to take in addition to the input parameters used, a link to view a breakdown of the steps involved, and the target nodes for this execution.

Let’s choose to go ahead and select Execute. Keep in mind that this may incur costs, so make sure to review them before executing. You can keep an eye on progress on this page as it goes through the steps to attempt to fix the issues on each node.

Aha! After the remediation is complete, we can see that Systems Manager has found and corrected issues with the SSM Agent with two nodes. This means that Systems Manager is able to connect with the SSM Agent running in those nodes successfully making them “managed nodes.” We can verify this by returning to the Explore nodes page and noticing that the count of “unmanaged nodes” has been reduced to zero now.

Now that all of our nodes are managed, we’re ready to get a full list of all of those that need to be added to our migration plan.

Step 4 – Downloading a report
Back on the Explore nodes page we can see that the count for nodes running Microsoft Windows Server 2016 Datacenter has gone up from ten to twelve! That means that those previously unmanaged nodes that we fixed through the automated diagnosis are indeed running our target operating system.

This is exactly what we need so we choose to download a Report. You give it a file name, and then choose from a few options such as which columns to include. In this case, we choose to download a CSV file with a row containing the column names.

That’s it! We have our CSV with detailed information about the nodes that need upgrading across our entire infrastructure. And the best part? You can also use Systems Manager to automate the upgrade once you’re ready to go ahead with the migration.

Conclusion
Systems Manager is a critical tool for gaining visibility and control over your compute infrastructure and performing operational actions at scale. The new experience offers a centralized cross-account, cross-Region view of all your nodes in your AWS accounts, on-premises, and multicloud environments through a centralized dashboard, offering integration with Amazon Q Developer for natural language queries, and one-click SSM Agent troubleshooting. You can enable the new experience at no extra cost by navigating to the Systems Manager console and following the straightforward instructions.

To learn more, see the documentation for more detail about the new Systems Manager experience.

Check out this interactive demo for a full visual tour of this experience.

Introducing generative AI troubleshooting for Apache Spark in AWS Glue (preview)

Post Syndicated from Noritaka Sekiyama original https://aws.amazon.com/blogs/big-data/introducing-generative-ai-troubleshooting-for-apache-spark-in-aws-glue-preview/

Organizations run millions of Apache Spark applications each month to prepare, move, and process their data for analytics and machine learning (ML). Building and maintaining these Spark applications is an iterative process, where developers spend significant time testing and troubleshooting their code. During development, data engineers often spend hours sifting through log files, analyzing execution plans, and making configuration changes to resolve issues. This process becomes even more challenging in production environments due to the distributed nature of Spark, its in-memory processing model, and the multitude of configuration options available. Troubleshooting these production issues requires extensive analysis of logs and metrics, often leading to extended downtimes and delayed insights from critical data pipelines.

Today, we are excited to announce the preview of generative AI troubleshooting for Spark in AWS Glue. This is a new capability that enables data engineers and scientists to quickly identify and resolve issues in their Spark applications. This feature uses ML and generative AI technologies to provide automated root cause analysis for failed Spark applications, along with actionable recommendations and remediation steps. This post demonstrates how you can debug your Spark applications with generative AI troubleshooting.

How generative AI troubleshooting for Spark works

For Spark jobs, the troubleshooting feature analyzes job metadata, metrics and logs associated with the error signature of your job to generates a comprehensive root cause analysis. You can initiate the troubleshooting and optimization process with a single click on the AWS Glue console. With this feature, you can reduce your mean time to resolution from days to minutes, optimize your Spark applications for cost and performance, and focus more on deriving value from your data.

Manually debugging Spark applications can get challenging for data engineers and ETL developers due to a few different reasons:

  • Extensive connectivity and configuration options to a variety of resources with Spark while makes it a popular data processing platform, often makes it challenging to root cause issues when configurations are not correct, especially related to resource setup (S3 bucket, databases, partitions, resolved columns) and access permissions (roles and keys).
  • Spark’s in-memory processing model and distributed partitioning of datasets across its workers while good for parallelism, often make it difficult for users to identify root cause of failures resulting from resource exhaustion issues like out of memory and disk exceptions.
  • Lazy evaluation of Spark transformations while good for performance, makes it challenging to accurately and quickly identify the application code and logic which caused the failure from the distributed logs and metrics emitted from different executors.

Let’s look at a few common and complex Spark troubleshooting scenarios where Generative AI Troubleshooting for Spark can save hours of manual debugging time required to deep dive and come up with the exact root cause.

Resource setup or access errors

Spark applications allows to integrate data from a variety of resources like datasets with several partitions and columns on S3 buckets and Data Catalog tables, use the associated job IAM roles and KMS keys for correct permissions to access these resources, and require these resources to exist and be available in the right regions and locations referenced by their identifiers. Users can mis-configure their applications that result in errors requiring deep dive into the logs to understand the root cause being a resource setup or permission issue.

Manual RCA: Failure reason and Spark application Logs

Following example shows the failure reason for such a common setup issue for S3 buckets in a production job run. The failure reason coming from Spark does not help understand the root cause or the line of code that needs to be inspected for fixing it.

Exception in User Class: org.apache.spark.SparkException : Job aborted due to stage failure: Task 0 in stage 0.0 failed 4 times, most recent failure: Lost task 0.3 in stage 0.0 (TID 3) (172.36.245.14 executor 1): com.amazonaws.services.glue.util.NonFatalException: Error opening file:

After deep diving into the logs of one of the many distributed Spark executors, it becomes clear that the error was caused due to a S3 bucket not existing, however the error stack trace is usually quite long and truncated to understand the precise root cause and location within Spark application where the fix is needed.

Caused by: java.io.IOException: com.amazon.ws.emr.hadoop.fs.shaded.com.amazonaws.services.s3.model.AmazonS3Exception: The specified bucket does not exist (Service: Amazon S3; Status Code: 404; Error Code: NoSuchBucket; Request ID: 80MTEVF2RM7ZYAN9; S3 Extended Request ID: AzRz5f/Amtcs/QatfTvDqU0vgSu5+v7zNIZwcjUn4um5iX3JzExd3a3BkAXGwn/5oYl7hOXRBeo=; Proxy: null), S3 Extended Request ID: AzRz5f/Amtcs/QatfTvDqU0vgSu5+v7zNIZwcjUn4um5iX3JzExd3a3BkAXGwn/5oYl7hOXRBeo=
at com.amazon.ws.emr.hadoop.fs.s3n.Jets3tNativeFileSystemStore.list(Jets3tNativeFileSystemStore.java:423)
at com.amazon.ws.emr.hadoop.fs.s3n.Jets3tNativeFileSystemStore.isFolderUsingFolderObject(Jets3tNativeFileSystemStore.java:249)
at com.amazon.ws.emr.hadoop.fs.s3n.Jets3tNativeFileSystemStore.isFolder(Jets3tNativeFileSystemStore.java:212)
at com.amazon.ws.emr.hadoop.fs.s3n.S3NativeFileSystem.getFileStatus(S3NativeFileSystem.java:518)
at com.amazon.ws.emr.hadoop.fs.s3n.S3NativeFileSystem.open(S3NativeFileSystem.java:935)
at com.amazon.ws.emr.hadoop.fs.s3n.S3NativeFileSystem.open(S3NativeFileSystem.java:927)
at org.apache.hadoop.fs.FileSystem.open(FileSystem.java:983)
at com.amazon.ws.emr.hadoop.fs.EmrFileSystem.open(EmrFileSystem.java:197)
at com.amazonaws.services.glue.hadoop.TapeHadoopRecordReaderSplittable.initialize(TapeHadoopRecordReaderSplittable.scala:168)
... 29 more

With Generative AI Spark Troubleshooting: RCA and Recommendations

With Spark Troubleshooting, you simply click the Troubleshooting analysis button on your failed job run, and the service analyzes the debug artifacts of your failed job to identify the root cause analysis along with the line number in your Spark application that you can inspect to further resolve the issue.

Spark Out of Memory Errors

Let’s take a common but relatively complex error that requires significant manual analysis to conclude its because of a Spark job running out of memory on Spark driver (master node) or one of the distributed Spark executors. Usually, troubleshooting requires an experienced data engineer to manually go over the following steps to identify the root cause.

  • Search through Spark driver logs to find the exact error message
  • Navigate to the Spark UI to analyze memory usage patterns
  • Review executor metrics to understand memory pressure
  • Analyze the code to identify memory-intensive operations

This process often takes hours because the failure reason from Spark is usually not challenging to understand that it was a out of memory issue on the Spark driver and what is the remedy to fix it.

Manual RCA: Failure reason and Spark application Logs

Following example shows the failure reason for the error.

Py4JJavaError: An error occurred while calling o4138.collectToPython. java.lang.StackOverflowError

Spark driver logs require extensive search to find the exact error message. In this case, the error stack trace consisted of more than hundred function calls and is challenging to understand the precise root cause as the Spark application terminated abruptly.

py4j.protocol.Py4JJavaError: An error occurred while calling o4138.collectToPython.
: java.lang.StackOverflowError
 at org.apache.spark.sql.catalyst.trees.TreeNode$$Lambda$1942/131413145.get$Lambda(Unknown Source)
 at org.apache.spark.sql.catalyst.trees.TreeNode.$anonfun$mapChildren$1(TreeNode.scala:798)
 at org.apache.spark.sql.catalyst.trees.TreeNode.mapProductIterator(TreeNode.scala:459)
 at org.apache.spark.sql.catalyst.trees.TreeNode.mapChildren(TreeNode.scala:781)
 at org.apache.spark.sql.catalyst.trees.TreeNode.clone(TreeNode.scala:881)
 at org.apache.spark.sql.catalyst.plans.logical.LogicalPlan.org$apache$spark$sql$catalyst$plans$logical$AnalysisHelper$$super$clone(LogicalPlan.scala:30)
 at org.apache.spark.sql.catalyst.plans.logical.AnalysisHelper.clone(AnalysisHelper.scala:295)
 at org.apache.spark.sql.catalyst.plans.logical.AnalysisHelper.clone$(AnalysisHelper.scala:294)
 at org.apache.spark.sql.catalyst.plans.logical.LogicalPlan.clone(LogicalPlan.scala:30)
 at org.apache.spark.sql.catalyst.plans.logical.LogicalPlan.clone(LogicalPlan.scala:30)
 at org.apache.spark.sql.catalyst.trees.TreeNode.$anonfun$clone$1(TreeNode.scala:881)
 at org.apache.spark.sql.catalyst.trees.TreeNode.applyFunctionIfChanged$1(TreeNode.scala:747)
 at org.apache.spark.sql.catalyst.trees.TreeNode.$anonfun$mapChildren$1(TreeNode.scala:783)
 at org.apache.spark.sql.catalyst.trees.TreeNode.mapProductIterator(TreeNode.scala:459)
 ... repeated several times with hundreds of function calls

With Generative AI Spark Troubleshooting: RCA and Recommendations

With Spark Troubleshooting, you can click the Troubleshooting analysis button on your failed job run and get a detailed root cause analysis with the line of code which you can inspect, and also recommendations on best practices to optimize your Spark application for fixing the problem.

Spark Out of Disk Errors

Another complex error pattern with Spark is when it runs out of disk storage on one of the many Spark executors in the Spark application. Similar to Spark OOM exceptions, manual troubleshooting requires extensive deep dive into distributed executor logs and metrics to understand the root cause and identify the application logic or code causing the error due to Spark’s lazy execution of its transformations.

Manual RCA: Failure Reason and Spark application Logs

The associated failure reason and error stack trace in the application logs is again quiet long requiring the user to gather more insights from Spark UI and Spark metrics to identify the root cause and identify the resolution.

An error occurred while calling o115.parquet. No space left on device
py4j.protocol.Py4JJavaError: An error occurred while calling o115.parquet.
: org.apache.spark.SparkException: Job aborted.
 at org.apache.spark.sql.errors.QueryExecutionErrors$.jobAbortedError(QueryExecutionErrors.scala:638)
 at org.apache.spark.sql.execution.datasources.FileFormatWriter$.write(FileFormatWriter.scala:279)
 at org.apache.spark.sql.execution.datasources.InsertIntoHadoopFsRelationCommand.run(InsertIntoHadoopFsRelationCommand.scala:193)
 at org.apache.spark.sql.execution.command.DataWritingCommandExec.sideEffectResult$lzycompute(commands.scala:113)
 at org.apache.spark.sql.execution.command.DataWritingCommandExec.sideEffectResult(commands.scala:111)
 at org.apache.spark.sql.execution.command.DataWritingCommandExec.executeCollect(commands.scala:125)
 ....

With Generative AI Spark Troubleshooting: RCA and Recommendations

With Spark Troubleshooting, it provides the RCA and the line number of code in the script where the data shuffle operation was lazily evaluated by Spark. It also points to best practices guide for optimizing the shuffle or wide transforms or using S3 shuffle plugin on AWS Glue.

Debug AWS Glue for Spark jobs

To use this troubleshooting feature for your failed job runs, complete following:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Choose your job.
  3. On the Runs tab, choose your failed job run.
  4. Choose Troubleshoot with AI to start the analysis.
  5. You will be redirected to the Troubleshooting analysis tab with generated analysis.

You will see Root Cause Analysis and Recommendations sections.

The service analyzes your job’s debug artifacts and provide the results. Let’s look at a real example of how this works in practice.

We show below an end-to-end example where Spark Troubleshooting helps a user with identification of the root cause for a resource setup issue and help fix the job to resolve the error.

Considerations

During preview, the service focuses on common Spark errors like resource setup and access issues, out of memory exceptions on Spark driver and executors, out of disk exceptions on Spark executors, and will clearly indicate when an error type is not yet supported. Your jobs must run on AWS Glue version 4.0.

The preview is available at no additional charge in all AWS commercial Regions where AWS Glue is available. When you use this capability, any validation runs triggered by you to test proposed solutions will be charged according to the standard AWS Glue pricing.

Conclusion

This post demonstrated how generative AI troubleshooting for Spark in AWS Glue helps your day-to-day Spark application debugging. It simplifies the debugging process for your Spark applications by using generative AI to automatically identify the root cause of failures and provides actionable recommendations to resolve the issues.

To learn more about this new troubleshooting feature for Spark, please visit Troubleshooting Spark jobs with AI.

A special thanks to everyone who contributed to the launch of generative AI troubleshooting for Apache Spark in AWS Glue: Japson Jeyasekaran, Rahul Sharma, Mukul Prasad, Weijing Cai, Jeremy Samuel, Hirva Patel, Martin Ma, Layth Yassin, Kartik Panjabi, Maya Patwardhan, Anshi Shrivastava, Henry Caballero Corzo, Rohit Das, Peter Tsai, Daniel Greenberg, McCall Peltier, Takashi Onikura, Tomohiro Tanaka, Sotaro Hikita, Chiho Sugimoto, Yukiko Iwazumi, Gyan Radhakrishnan, Victor Pleikis, Sriram Ramarathnam, Matt Sampson, Brian Ross, Alexandra Tello, Andrew King, Joseph Barlan, Daiyan Alamgir, Ranu Shah, Adam Rohrscheib, Nitin Bahadur, Santosh Chandrachood, Matt Su, Kinshuk Pahare, and William Vambenepe.


About the Authors

Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.

Vishal Kajjam is a Software Development Engineer on the AWS Glue team. He is passionate about distributed computing and using ML/AI for designing and building end-to-end solutions to address customers’ data integration needs. In his spare time, he enjoys spending time with family and friends.

Shubham Mehta is a Senior Product Manager at AWS Analytics. He leads generative AI feature development across services such as AWS Glue, Amazon EMR, and Amazon MWAA, using AI/ML to simplify and enhance the experience of data practitioners building data applications on AWS.

Wei Tang is a Software Development Engineer on the AWS Glue team. She is strong developer with deep interests in solving recurring customer problems with distributed systems and AI/ML.

XiaoRun Yu is a Software Development Engineer on the AWS Glue team. He is working on building new features for AWS Glue to help customers. Outside of work, Xiaorun enjoys exploring new places in the Bay Area.

Jake Zych is a Software Development Engineer on the AWS Glue team. He has deep interest in distributed systems and machine learning. In his spare time, Jake likes to create video content and play board games.

Savio Dsouza is a Software Development Manager on the AWS Glue team. His team works on distributed systems & new interfaces for data integration and efficiently managing data lakes on AWS.

Mohit Saxena is a Senior Software Development Manager on the AWS Glue team. His team focuses on building distributed systems to enable customers with interactive and simple-to-use interfaces to efficiently manage and transform petabytes of data across data lakes on Amazon S3, and databases and data warehouses on the cloud.

Introducing generative AI upgrades for Apache Spark in AWS Glue (preview)

Post Syndicated from Noritaka Sekiyama original https://aws.amazon.com/blogs/big-data/introducing-generative-ai-upgrades-for-apache-spark-in-aws-glue-preview/

Organizations run millions of Apache Spark applications each month on AWS, moving, processing, and preparing data for analytics and machine learning. As these applications age, keeping them secure and efficient becomes increasingly challenging. Data practitioners need to upgrade to the latest Spark releases to benefit from performance improvements, new features, bug fixes, and security enhancements. However, these upgrades are often complex, costly, and time-consuming.

Today, we are excited to announce the preview of generative AI upgrades for Spark, a new capability that enables data practitioners to quickly upgrade and modernize their Spark applications running on AWS. Starting with Spark jobs in AWS Glue, this feature allows you to upgrade from an older AWS Glue version to AWS Glue version 4.0. This new capability reduces the time data engineers spend on modernizing their Spark applications, allowing them to focus on building new data pipelines and getting valuable analytics faster.

Understanding the Spark upgrade challenge

The traditional process of upgrading Spark applications requires significant manual effort and expertise. Data practitioners must carefully review incremental Spark release notes to understand the intricacies and nuances of breaking changes, some of which may be undocumented. They then need to modify their Spark scripts and configurations, updating features, connectors, and library dependencies as needed.

Testing these upgrades involves running the application and addressing issues as they arise. Each test run may reveal new problems, resulting in multiple iterations of changes. After the upgraded application runs successfully, practitioners must validate the new output against the expected results in production. This process often turns into year-long projects that cost millions of dollars and consume tens of thousands of engineering hours.

How generative AI upgrades for Spark works

The Spark upgrades feature uses AI to automate both the identification and validation of required changes to your AWS Glue Spark applications. Let’s explore how these capabilities work together to simplify your upgrade process.

AI-driven upgrade plan generation

When you initiate an upgrade, the service analyzes your application using AI to identify necessary changes across both PySpark code and Spark configurations. During preview, Spark Upgrades supports upgrading from Glue 2.0 (Spark 2.4.3, Python 3.7) to Glue 4.0 (Spark 3.3.0, Python 3.10), automatically handling changes that would typically require extensive manual review of public Spark, Python and Glue version migration guides, followed by development, testing, and verification. Spark Upgrades addresses four key areas of changes:

  • Spark SQL API methods and functions
  • Spark DataFrame API methods and operations
  • Python language updates (including module deprecations and syntax changes)
  • Spark SQL and Core configuration settings

The complexity of these upgrades becomes evident when you consider migrating from Spark 2.4.3 to Spark 3.3.0 involves over a hundred version-specific changes. Several factors contribute to the challenges of performing manual upgrades:

  • Highly expressive language with a mix of imperative and declarative programming styles, allows users to easily develop Spark applications. However, this increases the complexity of identifying impacted code during upgrades.
  • Lazy execution of transformations in a distributed Spark application improves performance but makes runtime verification of application upgrades challenging for users.
  • Spark configurations changes in default values or the introduction of new configurations across versions can impact application behavior in different ways, making it difficult for users to identify issues during upgrades.

For example, in Spark 3.2, Spark SQL TRANSFORM operator can’t support alias in inputs. In Spark 3.1 and earlier, you could write a script transform like SELECT TRANSFORM(a AS c1, b AS c2) USING 'cat' FROM TBL.

# Original code (Glue 2.0)
query = """
SELECT TRANSFORM(item as product_name, price as product_price, number as product_number)
   USING 'cat'
FROM goods
WHERE goods.price > 5
"""
spark.sql(query)

# Updated code (Glue 4.0)
query = """
SELECT TRANSFORM(item, price, number)
   USING 'cat' AS (product_name, product_price, product_number)
FROM goods
WHERE goods.price > 5
"""
spark.sql(query)

In Spark 3.1, loading and saving timestamps before 1900-01-01 00:00:00Z as INT96 in Parquet files causes errors. In Spark 3.0, this wouldn’t fail but could result in timestamp shifts due to calendar rebasing. To restore the old behavior in Spark 3.1, you would need to configure the Spark SQL configurations for spark.sql.legacy.parquet.int96RebaseModeInRead and spark.sql.legacy.parquet.int96RebaseModeInWrite to LEGACY.

# Original code (Glue 2.0)
data = [(1, "1899-12-31 23:59:59"), (2, "1900-01-01 00:00:00")]
schema = StructType([ StructField("id", IntegerType(), True), StructField("timestamp", TimestampType(), True) ])
df = spark.createDataFrame(data, schema=schema)
df.write.mode("overwrite").parquet("path/to/parquet_file") 

# Updated code (Glue 4.0)
qspark.conf.set("spark.sql.legacy.parquet.int96RebaseModeInRead", "LEGACY") 
spark.conf.set("spark.sql.legacy.parquet.int96RebaseModeInWrite", "LEGACY")

data = [(1, "1899-12-31 23:59:59"), (2, "1900-01-01 00:00:00")]
schema = StructType([ StructField("id", IntegerType(), True), StructField("timestamp", TimestampType(), True) ])
df = spark.createDataFrame(data, schema=schema)
df.write.mode("overwrite").parquet("path/to/parquet_file")

Automated validation in your environment

After identifying the necessary changes, Spark Upgrades validates the upgraded application by running it as an AWS Glue job in your AWS account. The service iterates through multiple validation runs, up to 10, reviewing any errors encountered in each iteration and refining the upgrade plan until it achieves a successful run. You can run a Spark Upgrade Analysis in your development account using mock datasets supplied through Glue job parameters used for validation runs.

After Spark Upgrades has successfully validated the changes, it presents an upgrade plan for you to review. You can then accept and apply the changes to your job in the development account, before replicating them to your job in the production account. The Spark Upgrade plan includes the following:

  • An upgrade summary with an explanation of code updates made during the process
  • The final script that you can use in place of your current script
  • Logs from validation runs showing how issues were identified and resolved

You can review all aspects of the upgrade, including intermediate validation attempts and any error resolutions, before deciding to apply the changes to your production job. This approach ensures you have full visibility into and control over the upgrade process while benefiting from AI-driven automation.

Get started with generative AI Spark upgrades

Let’s walk through the process of upgrading an AWS Glue 2.0 job to AWS Glue 4.0. Complete the following steps:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Select your AWS Glue 2.0 job, and choose Run upgrade analysis with AI.
  3. For Result path, enter s3://aws-glue-assets-<account-id>-<region>/scripts/upgraded/ (provide your own account ID and AWS Region).
  4. Choose Run.
  5. On the Upgrade analysis tab, wait for the analysis to be completed.

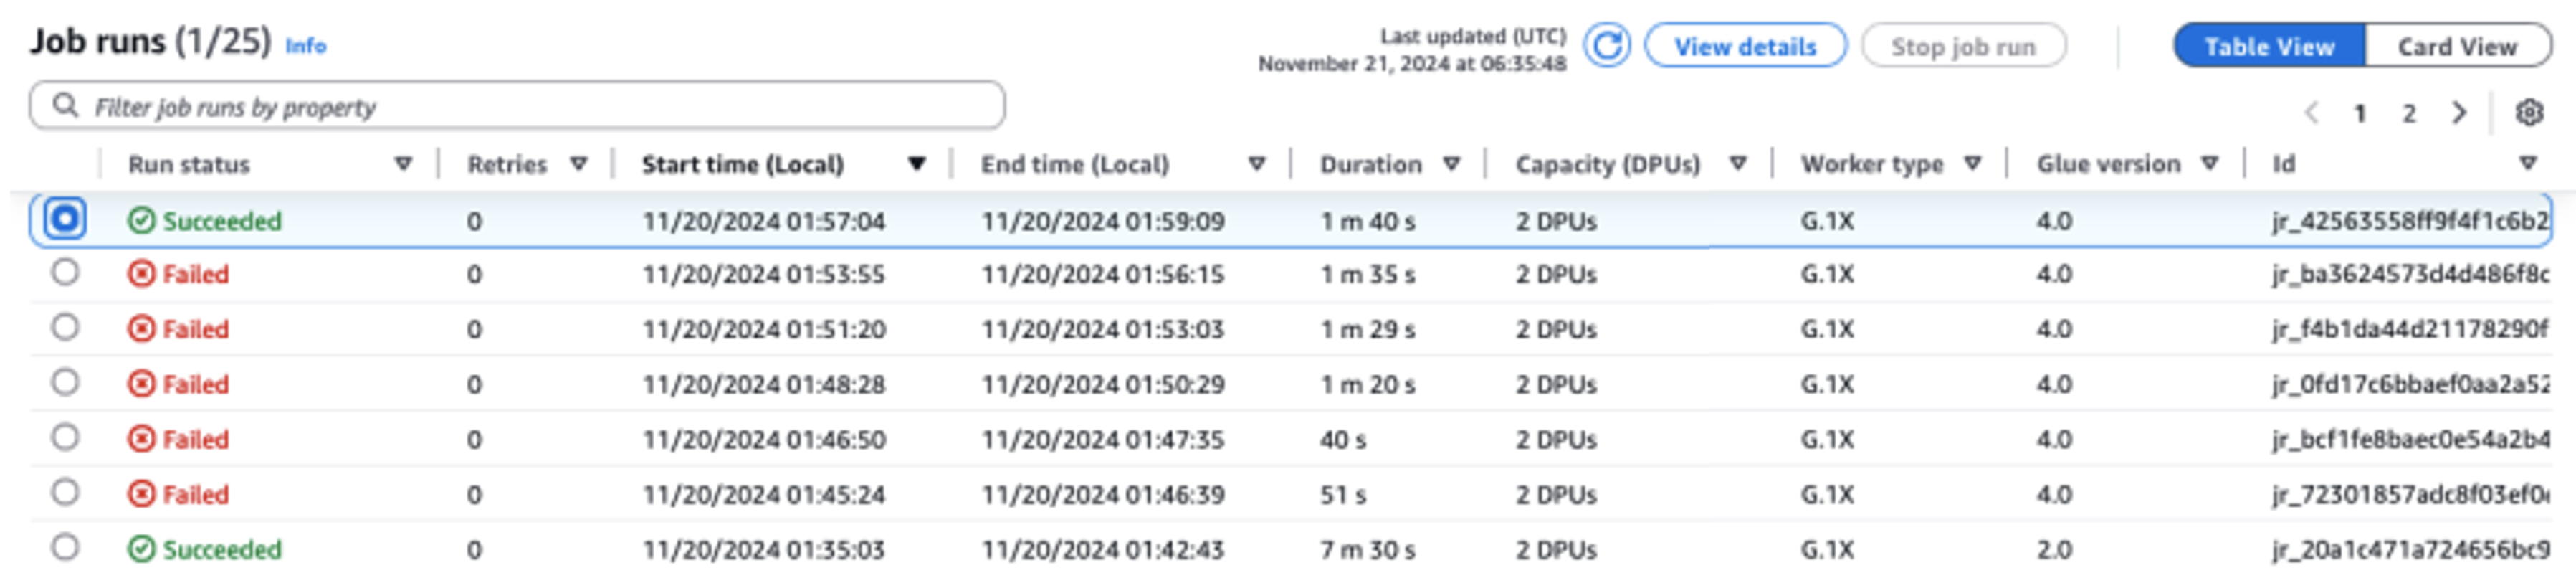
    While an analysis is running, you can view the intermediate job analysis attempts (up to 10) for validation under the Runs tab. Additionally, the Upgraded summary in S3 documents the upgrades made by the Spark Upgrade service so far, refining the upgrade plan with each attempt. Each attempt will display a different failure reason, which the service tries to address in the subsequent attempt through code or configuration updates.
    After a successful analysis, the upgraded script and a summary of changes will be uploaded to Amazon Simple Storage Service (Amazon S3).
  6. Review the changes to make sure they meet your requirements, then choose Apply upgraded script.

Your job has now been successfully upgraded to AWS Glue version 4.0. You can check the Script tab to verify the updated script and the Job details tab to review the modified configuration.

Understanding the upgrade process through an example

We now show a production Glue 2.0 job that we would like to upgrade to Glue 4.0 using the Spark Upgrade feature. This Glue 2.0 job reads a dataset, updated daily in an S3 bucket under different partitions, containing new book reviews from an online marketplace and runs SparkSQL to gather insights into the user votes for the book reviews.

Original code (Glue 2.0) – before upgrade

import sys
from awsglue.transforms import *
from awsglue.utils import getResolvedOptions
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from awsglue.job import Job
sc = SparkContext.getOrCreate()
glueContext = GlueContext(sc)
spark = glueContext.spark_session
job = Job(glueContext)
from collections import Sequence
from pyspark.sql.types import DecimalType
from pyspark.sql.functions import lit, to_timestamp, col

def is_data_type_sequence(coming_dict):
    return True if isinstance(coming_dict, Sequence) else False

def dataframe_to_dict_list(df):
    return [row.asDict() for row in df.collect()]

books_input_path = (
    "s3://aws-bigdata-blog/generated_synthetic_reviews/data/product_category=Books/"
)
view_name = "books_temp_view"
static_date = "2010-01-01"
books_source_df = (
    spark.read.option("header", "true")
    .option("recursiveFileLookup", "true")
    .option("path", books_input_path)
    .parquet(books_input_path)
)
books_source_df.createOrReplaceTempView(view_name)
books_with_new_review_dates_df = spark.sql(
    f"""
        SELECT 
        {view_name}.*,
            DATE_ADD(to_date(review_date), "180.8") AS next_review_date,
            CASE 
                WHEN DATE_ADD(to_date(review_date), "365") < to_date('{static_date}') THEN 'Yes' 
                ELSE 'No' 
            END AS Actionable
        FROM {view_name}
    """
)
books_with_new_review_dates_df.createOrReplaceTempView(view_name)
aggregate_books_by_marketplace_df = spark.sql(
    f"SELECT marketplace, count({view_name}.*) as total_count, avg(star_rating) as average_star_ratings, avg(helpful_votes) as average_helpful_votes, avg(total_votes) as average_total_votes  FROM {view_name} group by marketplace"
)
aggregate_books_by_marketplace_df.show()
data = dataframe_to_dict_list(aggregate_books_by_marketplace_df)
if is_data_type_sequence(data):
    print("data is valid")
else:
    raise ValueError("Data is invalid")

aggregated_target_books_df = aggregate_books_by_marketplace_df.withColumn(
    "average_total_votes_decimal", col("average_total_votes").cast(DecimalType(3, -2))
)
aggregated_target_books_df.show()

New code (Glue 4.0) – after upgrade

import sys
from awsglue.transforms import *
from awsglue.utils import getResolvedOptions
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from awsglue.job import Job
from collections.abc import Sequence
from pyspark.sql.types import DecimalType
from pyspark.sql.functions import lit, to_timestamp, col

sc = SparkContext.getOrCreate()
glueContext = GlueContext(sc)
spark = glueContext.spark_session
spark.conf.set("spark.sql.adaptive.enabled", "false")
spark.conf.set("spark.sql.legacy.allowStarWithSingleTableIdentifierInCount", "true")
spark.conf.set("spark.sql.legacy.allowNegativeScaleOfDecimal", "true")
job = Job(glueContext)

def is_data_type_sequence(coming_dict):
    return True if isinstance(coming_dict, Sequence) else False

def dataframe_to_dict_list(df):
    return [row.asDict() for row in df.collect()]

books_input_path = (
    "s3://aws-bigdata-blog/generated_synthetic_reviews/data/product_category=Books/"
)
view_name = "books_temp_view"
static_date = "2010-01-01"
books_source_df = (
    spark.read.option("header", "true")
    .option("recursiveFileLookup", "true")
    .load(books_input_path)
)
books_source_df.createOrReplaceTempView(view_name)
books_with_new_review_dates_df = spark.sql(
    f"""
        SELECT 
        {view_name}.*,
            DATE_ADD(to_date(review_date), 180) AS next_review_date,
            CASE 
                WHEN DATE_ADD(to_date(review_date), 365) < to_date('{static_date}') THEN 'Yes' 
                ELSE 'No' 
            END AS Actionable
        FROM {view_name}
    """
)
books_with_new_review_dates_df.createOrReplaceTempView(view_name)
aggregate_books_by_marketplace_df = spark.sql(
    f"SELECT marketplace, count({view_name}.*) as total_count, avg(star_rating) as average_star_ratings, avg(helpful_votes) as average_helpful_votes, avg(total_votes) as average_total_votes  FROM {view_name} group by marketplace"
)
aggregate_books_by_marketplace_df.show()
data = dataframe_to_dict_list(aggregate_books_by_marketplace_df)
if is_data_type_sequence(data):
    print("data is valid")
else:
    raise ValueError("Data is invalid")

aggregated_target_books_df = aggregate_books_by_marketplace_df.withColumn(
    "average_total_votes_decimal", col("average_total_votes").cast(DecimalType(3, -2))
)
aggregated_target_books_df.show()

Upgrade summary

In Spark 3.2, spark.sql.adaptive.enabled is enabled by default. To restore the behavior before Spark 3.2, 
you can set spark.sql.adaptive.enabled to false.

No suitable migration rule was found in the provided context for this specific error. The change was made based on the error message, which indicated that Sequence could not be imported from collections module. In Python 3.10, Sequence has been moved to the collections.abc module.

In Spark 3.1, path option cannot coexist when the following methods are called with path parameter(s): DataFrameReader.load(), DataFrameWriter.save(), DataStreamReader.load(), or DataStreamWriter.start(). In addition, paths option cannot coexist for DataFrameReader.load(). For example, spark.read.format(csv).option(path, /tmp).load(/tmp2) or spark.read.option(path, /tmp).csv(/tmp2) will throw org.apache.spark.sql.AnalysisException. In Spark version 3.0 and below, path option is overwritten if one path parameter is passed to above methods; path option is added to the overall paths if multiple path parameters are passed to DataFrameReader.load(). To restore the behavior before Spark 3.1, you can set spark.sql.legacy.pathOptionBehavior.enabled to true.

In Spark 3.0, the `date_add` and `date_sub` functions accepts only int, smallint, tinyint as the 2nd argument; fractional and non-literal strings are not valid anymore, for example: `date_add(cast('1964-05-23' as date), '12.34')` causes `AnalysisException`. Note that, string literals are still allowed, but Spark will throw `AnalysisException` if the string content is not a valid integer. In Spark version 2.4 and below, if the 2nd argument is fractional or string value, it is coerced to int value, and the result is a date value of `1964-06-04`.

In Spark 3.2, the usage of count(tblName.*) is blocked to avoid producing ambiguous results. Because count(*) and count(tblName.*) will output differently if there is any null values. To restore the behavior before Spark 3.2, you can set spark.sql.legacy.allowStarWithSingleTableIdentifierInCount to true.

In Spark 3.0, negative scale of decimal is not allowed by default, for example, data type of literal like 1E10BD is DecimalType(11, 0). In Spark version 2.4 and below, it was DecimalType(2, -9). To restore the behavior before Spark 3.0, you can set spark.sql.legacy.allowNegativeScaleOfDecimal to true.

As seen in the updated Glue 4.0 (Spark 3.3.0) script diff compared to the Glue 2.0 (Spark 2.4.3) script and the resulting upgrade summary, a total of six different code and configuration updates were applied across the six attempts of the Spark Upgrade Analysis.

  • Attempt #1 included a Spark SQL configuration (spark.sql.adaptive.enabled) to restore the application behavior as a new feature for Spark SQL adaptive query execution is introduced starting Spark 3.2. Users can inspect this configuration change and can further enable or disable it as per their preference.
  • Attempt #2 resolved a Python language change between Python 3.7 and 3.10 with the introduction of a new abstract base class (abc) under the Python collections module for importing Sequence.
  • Attempt #3 resolved an error encountered due to a change in behavior of DataFrame API starting Spark 3.1 where path option cannot exist with other DataFrameReader operations.
  • Attempt #4 resolved an error caused by a change in the Spark SQL function API signature for DATE_ADD which now only accepts integers as the second argument starting from Spark 3.0.
  • Attempt #5 resolved an error encountered due to the change in behavior Spark SQL function API for count(tblName.*) starting Spark 3.2. The behavior was restored with the introduction of a new Spark SQL configuration spark.sql.legacy.allowStarWithSingleTableIdentifierInCount
  • Attempt #6 successfully completed the analysis and ran the new script on Glue 4.0 without any new errors. The final attempt resolved an error encountered due to the prohibited use of negative scale for cast(DecimalType(3, -6) in Spark DataFrame API starting Spark 3.0. The issue was addressed by enabling the new Spark SQL configuration spark.sql.legacy.allowNegativeScaleOfDecimal.

Important considerations for preview

As you begin using automated Spark upgrades during the preview period, there are several important aspects to consider for optimal usage of the service:

  • Service scope and limitations – The preview release focuses on PySpark code upgrades from AWS Glue versions 2.0 to version 4.0. At the time of writing, the service handles PySpark code that doesn’t rely on additional library dependencies. You can run automated upgrades for up to 10 jobs concurrently in an AWS account, allowing you to efficiently modernize multiple jobs while maintaining system stability.
  • Optimizing costs during the upgrade process – Because the service uses generative AI to validate the upgrade plan through multiple iterations, with each iteration running as an AWS Glue job in your account, it’s essential to optimize the validation job run configurations for cost-efficiency. To achieve this, we recommend specifying a run configuration when starting an upgrade analysis as follows:
    • Using non-production developer accounts and selecting sample mock datasets that represent your production data but are smaller in size for validation with Spark Upgrades.
    • Using right-sized compute resources, such as G.1X workers, and selecting an appropriate number of workers for processing your sample data.
    • Enabling Glue auto scaling when applicable to automatically adjust resources based on workload.

    For example, if your production job processes terabytes of data with 20 G.2X workers, you might configure the upgrade job to process a few gigabytes of representative data with 2 G.2X workers and auto scaling enabled for validation.

  • Preview best practices – During the preview period, we strongly recommend starting your upgrade journey with non-production jobs. This approach allows you to familiarize yourself with the upgrade workflow, and understand how the service handles different types of Spark code patterns.

Your experience and feedback are crucial in helping us enhance and improve this feature. We encourage you to share your insights, suggestions, and any challenges you encounter through AWS Support or your account team. This feedback will help us improve the service and add capabilities that matter most to you during preview.

Conclusion

This post demonstrates how automated Spark upgrades can assist with migrating your Spark applications in AWS Glue. It simplifies the migration process by using generative AI to automatically identify the necessary script changes across different Spark versions.

To learn more about this feature in AWS Glue, see Generative AI upgrades for Apache Spark in AWS Glue.

A special thanks to everyone who contributed to the launch of generative AI upgrades for Apache Spark in AWS Glue: Shuai Zhang, Mukul Prasad, Liyuan Lin, Rishabh Nair, Raghavendhar Thiruvoipadi Vidyasagar, Tina Shao, Chris Kha, Neha Poonia, Xiaoxi Liu, Japson Jeyasekaran, Suthan Phillips, Raja Jaya Chandra Mannem, Yu-Ting Su, Neil Jonkers, Boyko Radulov, Sujatha Rudra, Mohammad Sabeel, Mingmei Yang, Matt Su, Daniel Greenberg, Charlie Sim, McCall Petier, Adam Rohrscheib, Andrew King, Ranu Shah, Aleksei Ivanov, Bernie Wang, Karthik Seshadri, Sriram Ramarathnam, Asterios Katsifodimos, Brody Bowman, Sunny Konoplev, Bijay Bisht, Saroj Yadav, Carlos Orozco, Nitin Bahadur, Kinshuk Pahare, Santosh Chandrachood, and William Vambenepe.


About the Authors

Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his new road bike.

Keerthi Chadalavada is a Senior Software Development Engineer at AWS Glue, focusing on combining generative AI and data integration technologies to design and build comprehensive solutions for customers’ data and analytics needs.

Shubham Mehta is a Senior Product Manager at AWS Analytics. He leads generative AI feature development across services such as AWS Glue, Amazon EMR, and Amazon MWAA, using AI/ML to simplify and enhance the experience of data practitioners building data applications on AWS.

Pradeep Patel is a Software Development Manager on the AWS Glue team. He is passionate about helping customers solve their problems by using the power of the AWS Cloud to deliver highly scalable and robust solutions. In his spare time, he loves to hike and play with web applications.

Chuhan LiuChuhan Liu is a Software Engineer at AWS Glue. He is passionate about building scalable distributed systems for big data processing, analytics, and management. He is also keen on using generative AI technologies to provide brand-new experience to customers. In his spare time, he likes sports and enjoys playing tennis.

Vaibhav Naik is a software engineer at AWS Glue, passionate about building robust, scalable solutions to tackle complex customer problems. With a keen interest in generative AI, he likes to explore innovative ways to develop enterprise-level solutions that harness the power of cutting-edge AI technologies.

Mohit Saxena is a Senior Software Development Manager on the AWS Glue and Amazon EMR team. His team focuses on building distributed systems to enable customers with simple-to-use interfaces and AI-driven capabilities to efficiently transform petabytes of data across data lakes on Amazon S3, and databases and data warehouses on the cloud.

Accelerate your data workflows with Amazon Redshift Data API persistent sessions

Post Syndicated from Dipal Mahajan original https://aws.amazon.com/blogs/big-data/accelerate-your-data-workflows-with-amazon-redshift-data-api-persistent-sessions/

Amazon Redshift is a fast, scalable, secure, and fully managed cloud data warehouse that you can use to analyze your data at scale. Tens of thousands of customers use Amazon Redshift to process exabytes of data to power their analytical workloads.The Amazon Redshift Data API simplifies programmatic access to Amazon Redshift data warehouses by providing a secure HTTP endpoint for executing SQL queries, so that you don’t have to deal with managing drivers, database connections, network configurations, authentication flows, and other connectivity complexities.

Amazon Redshift has launched a session reuse capability for the Data API that can significantly streamline multi-step, stateful workloads such as exchange, transform, and load (ETL) pipelines, reporting processes, and other flows that involve sequential queries. This persistent session model provides the following key benefits:

  1. The ability to create temporary tables that can be referenced across the entire session lifespan.
  2. Maintaining reusable database sessions to help optimize the use of database connections, preventing the API server from exhausting the available connections and improving overall system scalability.
  3. Reusing database sessions to simplify the connection management logic in your API implementation, reducing the complexity of the code and making it more straightforward to maintain and scale.
  4. Redshift Data API provides a secure HTTP endpoint and integration with AWS SDKs. You can use the endpoint to run SQL statements without managing connections. Calls to the Data API are asynchronous. The Data API uses either credentials stored in AWS Secrets Manager or temporary database credentials

A common use case that can particularly benefit from session reuse is ETL pipelines in Amazon Redshift data warehouses. ETL processes often need to stage raw data extracts into temporary tables, run a series of transformations while referencing those interim datasets, and finally load the transformed results into production data marts. Before session reuse was available, the multi-phase nature of ETL workflows meant that data engineers had to persist the intermediate results and repeatedly re-establish database connections after each step, which resulted in continually tearing down sessions; recreating, repopulating, and truncating temporary tables; and incurring overhead from connection cycling. The engineers could also reuse the entire API call, but this could lead to a single point of failure for the entire script because it doesn’t support restarting from the point where it failed.

With Data API session reuse, you can use a single long-lived session at the start of the ETL pipeline and use that persistent context across all ETL phases. You can create temporary tables once and reference them throughout, without having to constantly refresh database connections and restart from scratch.

In this post, we’ll walk through an example ETL process that uses session reuse to efficiently create, populate, and query temporary staging tables across the full data transformation workflow—all within the same persistent Amazon Redshift database session. You’ll learn best practices for optimizing ETL orchestration code, reducing job runtimes by reducing connection overhead, and simplifying pipeline complexity. Whether you’re a data engineer, an analyst generating reports, or working on any other stateful data, understanding how to use Data API session reuse is worth exploring. Let’s dive in!

Scenario

Imagine you’re building an ETL process to maintain a product dimension table for an ecommerce business. This table needs to track changes to product details over time for analysis purposes.

The ETL will:

  1. Load data extracted from the source system into a temporary table
  2. Identify new and updated products by comparing them to the existing dimension
  3. Merge the staged changes into the product dimension using a slowly changing dimension (SCD) Type 2 approach

Prerequisites

To walk through the example in this post, you need:

  • An AWS Account
  • An Amazon Redshift Serverless workgroup or provisioned cluster

Redshift Data API Commands

This command executes a Redshift Data API query to create a temporary table called stage_stores in Redshift.

 aws redshift-data execute-statement 
       --session-keep-alive-seconds 30 
       --sql "CREATE TEMP TABLE stage_stores (LIKE stores)" 
       --database dev 
       --workgroup-name blog_test

This command performs a COUNT(*) operation on the newly created table from the previous command, using the –session-id returned in the response of the first command.

 aws redshift-data execute-statement
    --sql "select count(*) from dev.stage_stores"
    --session-id 5a254dc6-4fc2-4203-87a8-551155432ee4
    --session-keep-alive-seconds 10

Solution walkthrough

  1. You will use AWS Step Functions to call the Data API because this is one of the more straightforward ways to create a codeless ETL. The first step is to load the extracted data into a temporary table.
    • Start by creating a temporary table based on the same columns as the final table using CREATE TEMP TABLE stage_stores (LIKE stores)”.
    • When using Redshift Serverless you must use WorkgroupName. If using Redshift Provisioned cluster, you should use ClusterIdentifier.

Temporary table creation

  1. In the next step, copy data from Amazon Simple Storage Service (Amazon S3) to the temporary table. Instead of re-establishing the session, reuse it.
    • Use SessionId and Sql as parameters.
    • Database is a required parameter for Step Functions, but it doesn’t have to have a value when using the SessionId.

Copy data to Redshift

  1. Lastly, use Merge to merge the target and temporary (source) tables to insert or update data based on the new data from the files.

Merge to Redshift

As shown in the preceding figures, we used a wait component because the query was fast enough for the session not to be captured. If the session isn’t captured, you will receive a Session is not available error. If you encounter that or a similar error, try adding a 1-second wait component.

At the end, the Data API use case should be completed, as shown in the following figure.

Step Function

Other relevant use cases

The Amazon Redshift Data API isn’t a replacement for JDBC and ODBC drivers and is suitable for use cases where you don’t need a persistent connection to a cluster. It’s applicable in the following use cases:

  • Accessing Amazon Redshift from custom applications with any programming language supported by the AWS SDK. This enables you to integrate web-based applications to access data from Amazon Redshift using an API to run SQL statements. For example, you can run SQL from JavaScript.
  • Building a serverless data processing workflow.
  • Designing asynchronous web dashboards because the Data API lets you run long-running queries without having to wait for it to complete.
  • Running your query one time and retrieving the results multiple times without having to run the query again within 24 hours.
  • Building your ETL pipelines with Step Functions, AWS Lambda, and stored procedures.
  • Having simplified access to Amazon Redshift from Amazon SageMaker and Jupyter Notebooks.
  • Building event-driven applications with Amazon EventBridgeand Lambda.
  • Scheduling SQL scripts to simplify data load, unload, and refresh of materialized views.

Key considerations for using session reuse

When you make a Data API request to run a SQL statement, if the parameter SessionKeepAliveSeconds isn’t set, the session where the SQL runs is terminated when the SQL is finished. To keep the session active for a specified number of seconds you must set SessionKeepAliveSeconds in the Data API ExecuteStatement and BatchExecuteStatement. A SessionId field will be present in the response JSON containing the identity of the session, which can then be used in subsequent ExecuteStatement and BatchExecuteStatement operations. In subsequent calls you can specify another SessionKeepAliveSeconds to change the idle timeout time. If the SessionKeepAliveSeconds isn’t changed, the initial idle timeout setting remains. Consider the following when using session reuse:

  • The maximum value of SessionKeepAliveSeconds is 24 hours. After 24 hours the session is forcibly closed, and in-progress queries are terminated.
  • The maximum number of sessions per Amazon Redshift cluster or Redshift Serverless workgroup is 500. Please refer to Redshift Quotas and Limits here.
  • It’s not possible to run parallel executions of the same session. You need to wait until the query is finished to run the next query in the same session. That is, you cannot run queries in parallel in a single session.
  • The Data API can’t queue queries for a given session.

Best practices

We recommend the following best practices when using the Data API:

  • Federate your IAM credentials to the database to connect with Amazon Redshift. Amazon Redshift allows users to get temporary database credentials with GetClusterCredentials. We recommend scoping the access to a specific cluster and database user if you’re granting your users temporary credentials. For more information, see Example policy for using GetClusterCredentials.
  • Use a custom policy to provide fine-grained access to the Data API in the production environment if you don’t want your users to use temporary credentials. You can use AWS Secrets Manager to manage your credentials in such use cases.
  • The maximum record size to be retrieved is 64 KB. More than that will raise an error.
  • Don’t retrieve a large amount of data from your client and use the UNLOAD command to export the query results to Amazon S3. You’re limited to retrieving no more than 100 MB of data using the Data API.
  • Query results are stored by 24 hours and discarded after that. If you need the same result after 24 hours, you will need to rerun the script to obtain the result.
  • Remember that the session will be available for the amount of time specified by the SessionKeepAliveSeconds parameter in the Redshift Data API call. The session will terminate after the specified duration.Based on your security requirements, configure this value according to your ETL and ensure sessions are properly closed by setting SessionKeepAliveSeconds to 1 second to terminate them.
  • When invoking Redshift API commands, all activities, including the user who executed the command and those who reused the session, are logged in CloudWatch. Additionally, you can configure alerts for monitoring.
  • If a Redshift session is terminated or closed and you attempt to access it via the API, you will receive an error message stating, “Session is not available.”

Conclusion

In this post, we introduced you to the newly launched Amazon Redshift Data API session reuse functionality. We also demonstrated how to use the Data API from the Amazon Redshift console query editor and Python using the AWS SDK. We also provided best practices for using the Data API.

To learn more, see Using the Amazon Redshift Data API or visit the Data API GitHub repository for code examples. For serverless, see Use the Amazon Redshift Data API to interact with Amazon Redshift Serverless.

—————————————————————————————————————————————————–

About the Author

Dipal Mahajan is a Lead Consultant with Amazon Web Services based out of India, where he guides global customers to build highly secure, scalable, reliable, and cost-efficient applications on the cloud. He brings extensive experience on Software Development, Architecture and Analytics from industries like finance, telecom, retail and healthcare.

Anusha Challa is a Senior Analytics Specialist Solutions Architect focused on Amazon Redshift. She has helped many customers build large-scale data warehouse solutions in the cloud and on premises. She is passionate about data analytics and data science.

Debu Panda is a Senior Manager, Product Management at AWS. He is an industry leader in analytics, application platform, and database technologies, and has more than 25 years of experience in the IT world.

Ricardo Serafim is a Senior Analytics Specialist Solutions Architect at AWS.

From data lakes to insights: dbt adapter for Amazon Athena now supported in dbt Cloud

Post Syndicated from Darshit Thakkar original https://aws.amazon.com/blogs/big-data/from-data-lakes-to-insights-dbt-adapter-for-amazon-athena-now-supported-in-dbt-cloud/

At AWS, we are committed to empowering organizations with tools that streamline data analytics and transformation processes. We are excited to announce that the dbt adapter for Amazon Athena is now officially supported in dbt Cloud. This integration enables data teams to efficiently transform and manage data using Athena with dbt Cloud’s robust features, enhancing the overall data workflow experience.

In this post, we discuss the advantages of dbt Cloud over dbt Core, common use cases, and how to get started with Amazon Athena using the dbt adapter.

The need for streamlined data transformations

As organizations increasingly adopt cloud-based data lakes and warehouses, the demand for efficient data transformation tools has grown. Athena plays a critical role in this ecosystem by providing a serverless, interactive query service that simplifies analyzing vast amounts of data stored in Amazon Simple Storage Service (Amazon S3) using standard SQL. This enables you to extract insights from your data without the complexity of managing infrastructure.

dbt has emerged as a leading framework, allowing data teams to transform and manage data pipelines effectively. With the dbt adapter for Athena adapter now supported in dbt Cloud, you can seamlessly integrate your AWS data architecture with dbt Cloud, taking advantage of the scalability and performance of Athena to simplify and scale your data workflows efficiently.

Benefits of the dbt adapter for Athena

We have collaborated with dbt Labs and the open source community on an adapter for dbt that enables dbt to interface directly with Athena. Previously, the dbt adapter for Athena was only compatible with dbt Core, requiring teams to manually manage configurations and execute transformations locally or through custom setups. Now, with support for dbt Cloud, you can access a managed, cloud-based environment that automates and enhances your data transformation workflows. This upgrade allows you to build, test, and deploy data models in dbt with greater ease and efficiency, using all the features that dbt Cloud provides.

The support of the dbt adapter for Athena in dbt Cloud offers several advantages over using it with dbt Core:

  • Managed infrastructure – dbt Cloud provides a fully managed environment for running dbt projects, eliminating the need for local setup, maintenance, and configuration. This saves time and effort, especially for teams looking to minimize infrastructure management and focus solely on data modeling.
  • Scheduling and automation – dbt Cloud comes with a job scheduler, allowing you to automate the execution of dbt models. This feature makes sure your datasets are always up to date without needing to set up and maintain external scheduling systems like Apache Airflow. You can also set up dependencies between jobs easily within dbt Cloud, making sure that transformations run in the correct sequence without manual oversight.
  • Enhanced collaboration and version control – You can use a web-based interface for editing and reviewing dbt models, enabling collaboration among data teams. You can review code changes directly on the platform, facilitating efficient teamwork. Additionally, dbt Cloud integrates with Git providers, making version control and code collaboration more streamlined. This makes sure your data models are well-documented, versioned, and straightforward to manage within a collaborative environment.
  • Monitoring and alerting – You get built-in tools for monitoring job executions and performance to set up alerts and notifications for job failures, providing quick response times and minimizing disruptions. Furthermore, you can gain insights into the performance of your data transformations with detailed execution logs and metrics, all accessible through the dbt Cloud interface.

Common use cases for using the dbt adapter with Athena

The following are common use cases for using the dbt adapter with Athena:

  • Building a data warehouse – Many organizations are moving towards a data warehouse architecture, combining the flexibility of data lakes with the performance and structure of data warehouses. Using Athena and the dbt adapter, you can transform raw data in Amazon S3 into well-structured tables suitable for analytics. This setup allows businesses to build a scalable and efficient data lakehouse where they can perform SQL-based transformations and make sure data is clean and ready for analytics without investing heavily in data warehouse infrastructure.
  • Incremental data processing – The adapter allows for incremental data processing, where only new or updated data is transformed and processed. This feature reduces the amount of data scanned by Athena, resulting in faster query performance and lower costs. For example, instead of processing an entire dataset daily, dbt can be configured to transform only the data ingested in the last 24 hours, making data operations more efficient and cost-effective.
  • Cost management and optimization – Because Athena charges based on the amount of data scanned by each query, cost optimization is critical. The adapter enables data teams to optimize transformations by creating efficient data models, such as partitioning and compressing data to minimize scan costs. Additionally, dbt’s automated scheduling in dbt Cloud can be used to manage the frequency of data transformations, making sure queries are run only when necessary, helping to control costs effectively.
  • Data archiving and tiered storage – Organizations with a large amount of historical data can use Athena to query archived data stored in the lower-cost storage classes of Amazon S3 (such as Amazon S3 Glacier). With the adapter, data teams can build models that segment and process data based on usage patterns, making sure frequently accessed data is optimized for quick queries while older data remains accessible but cost-efficient. Alternatively, you can use Amazon S3 Intelligent-Tiering to optimize storage costs by moving data between two access tiers when access patterns change. This approach helps in managing storage costs while maintaining the flexibility to analyze historical trends when needed.
  • Event-driven data transformations – In scenarios where organizations need to process data in near real time, such as for streaming event logs or Internet of Things (IoT) data, you can integrate the adapter into an event-driven architecture. For example, event data can be continuously loaded into Amazon S3, and dbt models can be configured to run incrementally, transforming the new data into structured formats for immediate analysis. This setup supports agile data processing while taking advantage of the serverless architecture of Athena to keep operational costs low.
  • Compliance and data governance – For organizations managing sensitive or regulated data, you can use Athena and the adapter to enforce data governance rules. With dbt, teams can define data quality checks and access controls as part of their transformation workflow. This makes sure that only compliant, high-quality data is made available for analytics, and costs are optimized by processing only the data that meets governance standards. Additionally, dbt’s documentation features help maintain a clear record of data transformations, supporting audit and compliance efforts.

How to use the dbt adapter for Athena

To get started, create a project and set up a connection with Athena in dbt Cloud. The following figure shows the steps to create a project using dbt Cloud and configure the Athena connection.

Next, use the dbt Cloud interactive development environment (IDE) to deploy your project. The following figure demonstrates how to build dbt runs and deploy changes to Athena using the dbt Cloud interface.

Conclusion

At AWS, we are committed to providing you with the best possible tools and services to help you succeed in the cloud. dbt has emerged as a leading data transformation platform, trusted by thousands of organizations worldwide. By partnering with dbt Labs, we are able to bring the power of dbt directly to the AWS Cloud, empowering you to seamlessly integrate your data transformation workflows into the broader cloud infrastructure. This partnership is a testament to our shared vision of making data more accessible, reliable, and valuable for organizations of all sizes.

We are excited to see how you will use the dbt Cloud compatible dbt adapter for Athena to drive your data-driven initiatives forward. The combination of dbt and Athena creates a powerful and efficient environment for transforming and analyzing data in a serverless architecture. This synergy allows you to take advantage of the strengths of both tools, making it straightforward to manage complex data pipelines, reduce costs, and scale your operations.


About the Authors

Darshit Thakkar is a Technical Product Manager with AWS and works with the Amazon Athena team.

Selman Ay is a Data Architect in the AWS Professional Services team.

BP Yau is a Sr Partner Solutions Architect at AWS helping customers architect big data solutions to process data at scale

Improve your app authentication workflow with new Amazon Cognito features

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/improve-your-app-authentication-workflow-with-new-amazon-cognito-features/

Introduced 10 years ago, Amazon Cognito is a service that helps you implement customer identity and access management (CIAM) in your web and mobile applications. You can use Amazon Cognito for various use cases, from providing your customers to quickly add sign-in and sign-up experiences to your applications and authorization to securing machine-to-machine authentication and enabling role-based access to AWS resources.

Today, I’m excited to share a series of significant updates to Amazon Cognito. These enhancements aim to provide you with more flexibility, improved security, and a better user experience for your applications.

Here’s a quick summary:

A new developer-focused console experience
Amazon Cognito now offers a streamlined getting-started experience featuring a quick wizard and use case-specific recommendations. This new approach helps you set up configurations and reach your end users faster and more efficiently than ever before.

This is the new Amazon Cognito flow to help you quickly set up your application. You can get started in three steps:

  1. Choose the type of application you need to build
  2. Configure the sign-in options according to the type of your application
  3. Follow the instructions to integrate the sign-in and sign-up pages with your application

Then, select Create.

Amazon Cognito then automatically creates your application and a new user pool, which is a user directory for authentication and authorization. From here, you can review your sign-in page by selecting View login page or get started with the example code for your application. Furthermore, Amazon Cognito supports major application frameworks and offers detailed instructions for integrating them using standard OpenID Connect (OIDC) and OAuth open source libraries.

This is the new overview dashboard for your application. The user pool dashboard now provides important information in the Details section, as well as a set of Recommendations to help you continue your development journey.

On this page, you can customize your users’ sign-in and sign-up experience with the Managed Login feature. This is a good segue for me to provide you with a quick overview of the next new feature.

Introducing Managed Login
The introduction of Managed Login brings a new level of customization to Amazon Cognito. Managed Login handles the heavy lifting of availability, scaling, and security for your company. Once integrated, you automatically get all the new security patches and future features without further code changes.

This feature allows you to create personalized sign-up and sign-in experiences that are a seamless part of your company’s application for your end users.

Before you can use Managed Login, you need to assign a domain. There are two ways to do this: use a prefix domain, a randomly generated sub-domain of Amazon Cognito domain, or use your own custom domain to provide your users with a familiar domain name.

Then, you can choose your Branding version, selecting either Managed login or classic Hosted UI.

If you’re an existing Amazon Cognito user, you might be familiar with the classic Hosted UI feature. Managed Login is the improved version of Hosted UI, offering a new collection of web interfaces for sign-up and sign-in, built-in responsiveness for different screen sizes, multi-factor authentication, and password-reset activities in your user pool.

With Managed Login, you can use the new branding designer, a no-code visual editor for managed login assets and style, and a set of API operations for programmatic configuration or deployment via infrastructure-as-code with AWS CloudFormation.

With the branding designer, you have the flexibility to customize the look and feel of the entire user journey, from sign up and sign in to password recovery and multi-factor authentication. This feature provides a real time preview and convenient shortcuts to preview screens in different screen sizes and display modes before you launch it.

You can learn more about Managed Login by visiting the Managed Login documentation page.

Passwordless login support
The Managed Login feature also offers pre-built integrations for passwordless authentication methods, including signing in with passkeys, email OTP (one-time-password) and SMS OTP. Passkey support allows users to authenticate using cryptographic keys stored securely on their devices, offering better security compared to traditional passwords. This capability helps you implement low-friction and secure authentication methods without the need to understand and implement WebAuthn related protocols.

By reducing the friction associated with traditional password-based sign-ins, this feature simplifies application access for your users while maintaining high security standards.

Visit the user pools authentication flow documentation page to learn more about the passwordless login support.

More options on pricing tiers: Lite, Essentials and Plus
Amazon Cognito has introduced new user pool feature tiers: Lite, Essentials, and Plus. These tiers are designed to cater to different customer needs and use cases with the Essentials tier being the default tier for new users pools created by customers. This new tier structure also allows you to choose the most appropriate option based on your application requirements, with the flexibility to switch between tiers as needed.

To check your current tier, you can go to your application dashboard and select Feature plan. You can also select Settings from the navigation menu.

On this page, you’ll get detailed information for each tier and the option to downgrade or upgrade your plan.

Here’s a quick overview of each tier:

  1. Lite tier: Existing features such as user registration, password-based authentication, and social identity provider integration are now packaged in this tier. If you’re an existing Amazon Cognito user, you can continue using these features without making changes to your user pools. 

  2. Essentials tier: Offers comprehensive authentication and access control features, allowing you to implement secure, scalable, and customized sign-up and sign-in experiences for your application within minutes. It includes all capabilities in Lite along with supporting Managed Login and passwordless login options using passkeys, email, or SMS. Essentials also supports customizing access tokens and disallowing password reuse.

  3. Plus tier: Builds upon the Essentials tier, focusing on elevated security needs. It includes all Essentials features plus threat protection capabilities against suspicious login activity, detection of compromised credentials, risk-based adaptive authentication, and the ability to export user authentication event logs for threat analysis.

Pricing for the Lite, Essentials and Plus tiers is based on monthly active users. Customers currently using the advanced security features of Amazon Cognito should consider the Plus tier, which includes all the advanced security features, additional capabilities such as passwordless, and up to 60 percent savings as compared to using the standalone advanced security features.

If you want to learn about these new pricing tiers, see the Amazon Cognito pricing page.

Things you need to know

  • Availability – The Essentials and Plus tier are available in all AWS Regions where Amazon Cognito is available except AWS GovCloud (US) Regions.
  • Free tier on Lite and Essentials tiers – Customers on the Lite and Essentials tiers can enjoy the free tier each month that does not automatically expire. It is available to both existing and new AWS customers indefinitely. For more details on free tier, please visit the Amazon Cognito pricing page.

  • Extended pricing benefit for existing customers – Customers are eligible to upgrade their user pools without advanced security features (ASF) in their existing accounts to Essentials and pay the same price as Cognito user pools until November 30, 2025. To be eligible, customers’ accounts must have had at least 1 monthly active user (MAU) in the last 12 months on or before 10:00am Pacific Time, November 22, 2024. These customers are also eligible to create new user pools with Essentials tier at the same price as Cognito users pools in those accounts until November 30, 2025.

With these updates, you can implement secure, scalable, and customizable authentication solutions for your applications with Amazon Cognito.

Happy building,
— Donnie

Node.js 22 runtime now available in AWS Lambda

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/node-js-22-runtime-now-available-in-aws-lambda/

This post is written by Julian Wood, Principal Developer Advocate, and Andrea Amorosi, Senior SA Engineer.

You can now develop AWS Lambda functions using the Node.js 22 runtime, which is in active LTS status and ready for production use. Node.js 22 includes a number of additions to the language, including require()ing ES modules, as well as changes to the runtime implementation and the standard library. With this release, Node.js developers can take advantage of these new features and enhancements when creating serverless applications on Lambda.

You can develop Node.js 22 Lambda functions using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDK for JavaScript, AWS Serverless Application Model (AWS SAM), AWS Cloud Development Kit (AWS CDK), and other infrastructure as code tools.

To use this new version, specify a runtime parameter value of nodejs22.x when creating or updating functions or by using the appropriate container base image.

You can use Node.js 22 with Powertools for AWS Lambda (TypeScript), a developer toolkit to implement serverless best practices and increase developer velocity. Powertools for AWS Lambda includes libraries to support common tasks such as observability, AWS Systems Manager Parameter Store integration, idempotency, batch processing, and more. You can also use Node.js 22 with Lambda@Edge to customize low-latency content delivered through Amazon CloudFront.

This blog post highlights important changes to the Node.js runtime, notable Node.js language updates, and how you can use the new Node.js 22 runtime in your serverless applications.

Node.js 22 language updates

Node.js 22 introduces several language updates and features that enhance developer productivity and improve application performance.

This release adds support for loading ECMAScript modules (ESM) using require(). You can enable this feature using the --experimental-require-module flag by configuring the NODE_OPTIONS environment variable. require() support for synchronous ESM graphs bridges the gap between CommonJS and ESM, providing more flexibility in module loading. It is important to note that this feature is currently experimental and may change in future releases.

WebSocket support which was previously available behind the --experimental-websocket flag is now enabled by default in Node.js 22. This brings a browser-compatible WebSocket client implementation to Node.js with no need for external dependencies. Native support simplifies building real-time applications and enhances the overall WebSocket experience in Node.js environments.

The new runtime also includes performance improvements to AbortSignal creation. This makes network operations faster and more efficient for the Fetch API and test runner. The Fetch API is also now considered stable in Node.js 22.

For TypeScript users, Node.js 22 introduces experimental support for transforming TypeScript-only syntax into JavaScript code. By using the --experimental-transform-types flag, you can enable this feature to support TypeScript syntax such as Enum and namespace directly. While you can enable the feature in Lambda, your function entrypoint (i.e. index.mjs or app.cjs) cannot currently be written using TypeScript as the runtime expects a file with a JavaScript extension. You can use TypeScript for any other module imported within your codebase.

For a detailed overview of Node.js 22 language features, see the Node.js 22 release blog post and the Node.js 22 changelog.

Experimental features that are unavailable

Node.js 22 includes an experimental feature to detect the module syntax automatically (CommonJS or ES Modules). This feature must be enabled when the Node.js runtime is compiled. Since the Lambda-provided Node.js 22 runtime is intended for production workloads, this experimental feature is not enabled in the Lambda build and cannot be enabled via an execution-time flag. To use this feature in Lambda, you need to deploy your own Node.js runtime using a custom runtime or container image with experimental module syntax detection enabled.

Performance considerations

At launch, new Lambda runtimes receive less usage than existing established runtimes. This can result in longer cold start times due to reduced cache residency within internal Lambda sub-systems. Cold start times typically improve in the weeks following launch as usage increases. As a result, AWS recommends not drawing conclusions from side-by-side performance comparisons with other Lambda runtimes until the performance has stabilized. Since performance is highly dependent on workload, customers with performance-sensitive workloads should conduct their own testing, instead of relying on generic test benchmarks.

Builders should continue to measure and test function performance and optimize function code and configuration for any impact. To learn more about how to optimize Node.js performance in Lambda, see Performance optimization in the Lambda Operator Guide, and our blog post Optimizing Node.js dependencies in AWS Lambda.

Migration from earlier Node.js runtimes

AWS SDK for JavaScript

Up until Node.js 16, Lambda’s Node.js runtimes included the AWS SDK for JavaScript version 2. This has since been superseded by the AWS SDK for JavaScript version 3, which was released in December 2022. Starting with Node.js 18, and continuing with Node.js 22, the Lambda Node.js runtimes include version 3. When upgrading from Node.js 16 or earlier runtimes and using the included version 2, you must upgrade your code to use the v3 SDK.

For optimal performance, and to have full control over your code dependencies, we recommend bundling and minifying the AWS SDK in your deployment package, rather than using the SDK included in the runtime. For more information, see Optimizing Node.js dependencies in AWS Lambda.

Amazon Linux 2023

The Node.js 22 runtime is based on the provided.al2023 runtime, which is based on the Amazon Linux 2023 minimal container image. The Amazon Linux 2023 minimal image uses microdnf as a package manager, symlinked as dnf. This replaces the yum package manager used in Node.js 18 and earlier AL2-based images. If you deploy your Lambda function as a container image, you must update your Dockerfile to use dnf instead of yum when upgrading to the Node.js 22 base image from Node.js 18 or earlier.

Additionally AL2 includes curl and gnupg2 as their minimal versions curl-minimal and gnupg2-minimal.

Learn more about the provided.al2023 runtime in the blog post Introducing the Amazon Linux 2023 runtime for AWS Lambda and the Amazon Linux 2023 launch blog post.

Using the Node.js 22 runtime in AWS Lambda

AWS Management Console

To use the Node.js 22 runtime to develop your Lambda functions, specify a runtime parameter value Node.js 22.x when creating or updating a function. The Node.js 22 runtime version is now available in the Runtime dropdown on the Create function page in the AWS Lambda console:

Creating Node.js function in AWS Management Console

Creating Node.js function in AWS Management Console

To update an existing Lambda function to Node.js 22, navigate to the function in the Lambda console, then choose Node.js 22.x in the Runtime settings panel. The new version of Node.js is available in the Runtime dropdown:

Changing a function to Node.js 22

Changing a function to Node.js 22

AWS Lambda container image

Change the Node.js base image version by modifying the FROM statement in your Dockerfile.

FROM public.ecr.aws/lambda/nodejs:22
# Copy function code
COPY lambda_handler.xx ${LAMBDA_TASK_ROOT}

AWS Serverless Application Model (AWS SAM)

In AWS SAM, set the Runtime attribute to node22.x to use this version:

AWSTemplateFormatVersion: "2210-09-09"
Transform: AWS::Serverless-2216-10-31

Resources:
  MyFunction:
    Type: AWS::Serverless::Function
    Properties:
      Handler: lambda_function.lambda_handler
      Runtime: nodejs22.x
      CodeUri: my_function/.
      Description: My Node.js Lambda Function

When you add function code directly in an AWS SAM or AWS CloudFormation template as an inline function, it is seen as common.js.

AWS SAM supports generating this template with Node.js 22 for new serverless applications using the sam init command. Refer to the AWS SAM documentation.

AWS Cloud Development Kit (AWS CDK)

In AWS CDK, set the runtime attribute to Runtime.NODEJS_22_X to use this version.

import * as cdk from "aws-cdk-lib";
import * as lambda from "aws-cdk-lib/aws-lambda";
import * as path from "path";
import { Construct } from "constructs";

export class CdkStack extends cdk.Stack {
  constructor(scope: Construct, id: string, props?: cdk.StackProps) {
    super(scope, id, props);

    // The code that defines your stack goes here

    // The Node.js 22 enabled Lambda Function
    const lambdaFunction = new lambda.Function(this, "node22LambdaFunction", {
      runtime: lambda.Runtime.NODEJS_22_X,
      code: lambda.Code.fromAsset(path.join(__dirname, "/../lambda")),
      handler: "index.handler",
    });
  }
}


Conclusion

Lambda now supports Node.js 22 as a managed language runtime. This release uses the Amazon Linux 2023 OS as well as other improvements detailed in this blog post.

You can build and deploy functions using Node.js 22 using the AWS Management Console, AWS CLI, AWS SDK, AWS SAM, AWS CDK, or your choice of infrastructure as code tool. You can also use the Node.js 22 container base image if you prefer to build and deploy your functions using container images.

The Node.js 22 runtime helps developers build more efficient, powerful, and scalable serverless applications. Read about the Node.js programming model in the Lambda documentation to learn more about writing functions in Node.js 22. Try the Node.js runtime in Lambda today.

For more serverless learning resources, visit Serverless Land.

Introducing new capabilities to AWS CloudTrail Lake to enhance your cloud visibility and investigations

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/introducing-new-capabilities-to-aws-cloudtrail-lake-to-enhance-your-cloud-visibility-and-investigations/

Today, I’m excited to announce new updates to AWS CloudTrail Lake, which is a managed data lake you can use to aggregate, immutably store, and query events recorded by AWS CloudTrail for auditing, security investigation, and operational troubleshooting.

The new updates in CloudTrail Lake are:

  • Enhanced filtering options for CloudTrail events
  • Cross-account sharing of event data stores
  • General availability of the generative AI–powered natural language query generation
  • AI-powered query results summarization capability in preview
  • Comprehensive dashboard capabilities, including a high-level overview dashboard with AI-powered insights (AI-powered insights is in preview), a suite of 14 pre-built dashboards for various use cases, and the ability to create custom dashboards with scheduled refreshes

Let’s look into the new features one by one.

Enhanced filtering options for CloudTrail events ingested into event data stores
Enhanced event filtering capabilities give you greater control over which CloudTrail events are ingested into your event data stores. These enhanced filtering options provide tighter control over your AWS activity data, improving the efficiency and precision of security, compliance, and operational investigations. Additionally, the new filtering options help you reduce your analysis workflow costs by ingesting only the most relevant event data into your CloudTrail Lake event data stores.

You can filter both management and data events based on attributes such as eventSource, eventType, eventName, userIdentity.arn, and sessionCredentialFromConsole.

I go to the AWS CloudTrail console and choose Event data stores under Lake in the navigation pane. I choose Create event data store. In the first step, I enter a name in the Event data store name field. For this demo, I leave other fields as default. You can choose the pricing and retention options that suit your needs. In the next step, I choose Managements events and Data events under CloudTrail events. You can include all the options you need under CloudTrail events. You also have the option to choose ingestion options. I choose Ingest events to start ingesting when it’s created. There may be scenarios, when you want to deselect the Ingest events option to stop an event data store from ingesting events. For example, you may be copying trail events to the event data store and do not want the event data store to collect any future events. You can also choose to enable ingestion for all accounts in your organization or include only the current region in your event data store.

The following example shows an out of the box template for filtering, which excludes any management events that are initiated by an AWS Service. I choose Advanced event collection under the Management events. I choose Exclude AWS service-initiated events from the Log selector template dropdown. You can also expand the JSON view to see how the filters actually apply.

Under the Data events, the following example creates a filter to include DynamoDB data events initiated by a certain user, helping me to log events based on an IAM principal. I choose DynamoDB as Resource type. I choose Custom as Log selector template. Under the Advanced event selector, I choose userIdentity.arn as Field and equals as Operator. I enter the user’s ARN as Value. I choose Next and choose Create event data store in the final step.

Now, I have my event data store that gives me granular control over the ingested CloudTrail data.

This expanded set of filtering options helps you to be more selective in capturing only the most relevant events for your security, compliance, and operational needs.

Cross-account sharing of event data stores
You can use the cross-account sharing feature of event data stores to enhance collaborative analysis within organizations. It enables secure sharing of event data stores with selected AWS principals through Resource-Based Policies (RBP). This functionality allows authorized entities to query shared event data stores within the same AWS Region where they were created. 

To use this feature, I go to the AWS CloudTrail console and choose Event data stores under Lake in the navigation pane. I choose an event data store from the list and navigate to its details page. I choose Edit in the Resource policy section. The following example policy includes a statement that allows root users in accounts 111111111111, 222222222222, and 333333333333 to run queries and get query results on the event data store owned by account ID 999999999999. I choose Save changes to save the policy.

Generative AI–powered natural language query generation in CloudTrail Lake is now generally available
In June, we announced this feature for CloudTrail Lake in preview. With this launch, you can generate SQL queries using natural language questions to easily explore and analyze AWS activity logs (only management, data, and network activity events) without needing technical SQL expertise. The feature uses generative AI to convert natural language questions into ready-to-use SQL queries you can run directly in the CloudTrail Lake console. This simplifies the process of exploring event data stores and retrieving insights such as error counts, top services used, and the causes of errors. This feature is also accessible through the AWS Command Line Interface (AWS CLI), providing additional flexibility for users who prefer command-line operations. The preview blog post provides step-by-step instructions on how to get started with the natural language query generation feature in CloudTrail Lake.

CloudTrail Lake generative AI–powered query results summarization capability in preview
Building on the capability of natural language query generation, we’re introducing a new AI-powered query results summarization feature in preview to further simplify the process of analyzing AWS account activity. With this feature, you can easily extract valuable insights from your AWS activity logs (only management, data, and network activity events) by automatically summarizing the key points from your query results in natural language, reducing the time and effort required to understand the information.

To try this feature, I go to the AWS CloudTrail console and choose Query under Lake in the navigation pane. I choose an event data store for my CloudTrail Lake query from the dropdown list in Event data store. You can use summarization regardless of whether the query was written manually or generated by generative AI. For this example, I will use the natural language query generation capability. In the Query generator, I enter the following prompt in the Prompt field using natural language:

How many errors were logged during the past month for each service and what was the cause of each error?

Then, I choose Generate query. The following SQL query is automatically generated:

SELECT eventsource,
    errorcode,
    errormessage,
    count(*) as errorcount
FROM a0******
WHERE eventtime >= '2024-10-14 00:00:00'
    AND eventtime <= '2024-11-14 23:59:59'
    AND (
        errorcode IS NOT NULL
        OR errormessage IS NOT NULL
    )
GROUP BY 1,
    2,
    3
ORDER BY 4 DESC;

I choose Run to get the results. To use the summarization capability, I choose Summarize results in the Query results tab. CloudTrail automatically analyzes the query results and provides a natural language summary of the key insights. It’s important to note that there’s a monthly quota of 3 MB for query results that can be summarized.

This new summarization capability can save you time and effort in understanding your AWS activity data by automatically generating meaningful summaries of the key findings.

Comprehensive dashboard capabilities
Lastly, let me tell you about the new dashboard capabilities of CloudTrail Lake to enhance visibility and analysis across your AWS environments.

The first one is a Highlights dashboard that provides you with an easy-to-view summary of the data captured in your CloudTrail Lake management and data events stored in event data stores. This dashboard makes it easier to quickly identify and understand important insights, such as the top failed API calls, trends in failed login attempts, and spikes in resource creation. It surfaces any anomalies or unusual trends in the data.

I go to the AWS CloudTrail console and choose Dashboard under Lake in the navigation pane to check out the Highlights dashboard. First, I enable Highlights dashboard by choosing Agree and enable Highlights.

I check out the Highlights dashboard once it populates with data.

The second addition to the new dashboard capabilities is a suite of 14 pre-built dashboards. These dashboards are designed for different personas and use cases. For example, the security-focused dashboards help you to track and analyze key security indicators, such as top access denied events, failed console login attempts, and users who have disabled multi-factor authentication (MFA). There are also pre-built dashboards for operational monitoring, highlighting trends in errors and availability issues, such as top APIs with throttling errors and top users with errors. You can also use the dashboards focused on specific AWS services such as Amazon EC2 and Amazon DynamoDB, which help you identify security risks or operational problems within those particular service environments.

You can create your own dashboards and optionally set schedules for refreshing them. This level of customization helps you tailor the CloudTrail Lake analysis capabilities to your precise monitoring and investigative needs across your AWS environments.

I switch to the Managed and custom dashboards to observe the custom and pre-built dashboards.

I choose IAM activity dashboard pre-built dashboard to observe overall IAM activity. You can choose Save as new dashboard to customize this dashboard.

To create a custom dashboard from scratch, I go to Dashboard under Lake in the navigation pane and choose Build my own dashboard. I enter a name in the Enter a name for the dashboard field and choose event data stores under Permissions, to visualize the events. Next, I choose Create dashboard.

Now, I can add widgets to my dashboard. You have the flexibility to customize your dashboards in multiple ways. You can select from a list of pre-built sample widgets using Add sample widget, or you can create your own custom widgets using Create new widget. For each widget, you can choose the type of visualization you prefer, such as a line graph, bar graph, or other options to best represent your data.

Now available
The new features in AWS CloudTrail Lake represent a major advancement in providing a comprehensive audit logging and analysis solution. These enhancements provide the ability to gain more profound understanding and conduct investigations more rapidly, assisting with more preventative monitoring and faster incident handling across your entire AWS environments.

You can now start using generative AI–powered natural language query generation in CloudTrail Lake in US East (N. Virginia), US West (Oregon), Asia Pacific (Mumbai), Asia Pacific (Sydney), Asia Pacific (Tokyo), Canada (Central), and Europe (London) AWS Regions.

CloudTrail Lake generative AI–powered query results summarization capability is available in preview in US East (N. Virginia), US West (Oregon), and Asia Pacific (Tokyo) Regions.

Enhanced filtering options, cross-account sharing of event data stores and dashboards are available in all the Regions where CloudTrail Lake is available, with the exception of generative AI–powered summarization feature on the Highlights dashboard being available only in US East (N. Virginia), US West (Oregon), and Asia Pacific (Tokyo) Regions.

Running queries will incur CloudTrail Lake query charges. For more details on pricing, visit AWS CloudTrail pricing.

— Esra

AWS Glue Data Catalog supports automatic optimization of Apache Iceberg tables through your Amazon VPC

Post Syndicated from Noritaka Sekiyama original https://aws.amazon.com/blogs/big-data/aws-glue-data-catalog-supports-automatic-optimization-of-apache-iceberg-tables-through-your-amazon-vpc/

The AWS Glue Data Catalog supports automatic table optimization of Apache Iceberg tables, including compaction, snapshots, and orphan data management. The data compaction optimizer constantly monitors table partitions and kicks off the compaction process when the threshold is exceeded for the number of files and file sizes.

The Iceberg table compaction process starts and will continue if the table or any of the partitions within the table has more than the configured number of files (default five files), each smaller than 75% of the target file size. The snapshot retention process runs periodically (default daily) to identify and remove snapshots that are older than the specified retention configuration from the table properties, while keeping the most recent snapshots up to the configured limit. Similarly, the orphan file deletion process scans the table metadata and the actual data files, identifies the unreferenced files, and deletes them to reclaim storage space. These storage optimizations can help you reduce metadata overhead, control storage costs, and improve query performance.

Although automatic table optimization has simplified day-to-day Iceberg table maintenance tasks, certain industries and customers have advanced requirements to access their Iceberg tables from specific virtual private clouds (VPCs). This access control is needed for not only data ingestion and querying, but also for table maintenance.

To help achieve such requirements, we provide the capability where the Data Catalog optimizes Iceberg tables to run in your specific VPC. This post demonstrates how it works with step-by-step instructions.

How the table optimizer works with AWS Glue network connection

By default, a table optimizer is not associated with any of your VPCs and subnets. With this new capability of supporting data access from VPCs, you can associate a table optimizer with an AWS Glue network connection to run in a specific VPC, subnet, and security group. An AWS Glue network connection is commonly used to run an AWS Glue job with a specific VPC, subnet, and security group. The following diagram illustrates how it works.

In the next sections, we demonstrate how to configure a table optimizer with an AWS Glue network connection.

Prerequisites

To run through this instruction, you must have the following prerequisites:

Set up resources with AWS CloudFormation

This post includes a sample AWS CloudFormation template that enables a quick setup of the solution resources. You can review and customize the template to suit your needs.

The CloudFormation template generates the following resources:

  • An Amazon Simple Storage Service (Amazon S3) bucket to store the dataset, AWS Glue job scripts, and so on. (See Appendix 1 at the end of this post for manual instructions.)
  • A Data Catalog database.
  • An AWS Glue job that creates and modifies sample customer data in your S3 bucket with a trigger every 10 minutes.
  • AWS IAM roles and policies.
  • A VPC, public subnet, two private subnets, internet gateway, and route tables.
  • Amazon Virtual Private Cloud (Amazon VPC) endpoints for AWS Glue, AWS Lake Formation, Amazon CloudWatch, Amazon S3, and AWS Security Token Service (AWS STS). The endpoint names are as follows:
    • AWS Glue – com.amazonaws.<region>.glue (for example, com.amazonaws.us-east-1.glue).
    • Lake Formation – com.amazonaws.<region>.lakeformation (only if tables are registered with Lake Formation).
    • CloudWatch – com.amazonaws.<region>.monitoring.
    • Amazon S3 – com.amazonaws.<region>.s3.
    • AWS STS – com.amazonaws.<region>.sts.
  • An AWS Glue network connection configured with the VPC and subnet. (See Appendix 2 at the end of this post for manual instructions.)

To launch the CloudFormation stack, complete the following steps:

  1. Sign in to the AWS CloudFormation console.
  2. Choose Launch Stack.
    Launch Stack
  3. Choose Next.
  4. For SubnetAz1, choose your preferred Availability Zone.
  5. For SubnetAz2, choose your preferred Availability Zone. This needs to be different from SubnetAz1.
  6. Leave the other parameters as default or make appropriate changes based on your requirements, then choose Next.
  7. Review the details on the final page and select I acknowledge that AWS CloudFormation might create IAM resources.
  8. Choose Create.

This stack can take around 5–10 minutes to complete, after which you can view the deployed stack on the AWS CloudFormation console.

Configure automatic table optimization with an AWS Glue network connection

Complete following steps to configure automatic table optimization with an AWS Glue network connection:

  1. On the AWS Glue console, choose Databases in the navigation pane.
  2. Choose iceberg_optimizer_vpc_db.
  3. Under Tables, choose customer.
  4. On the Table optimization – new tab, choose Enable optimization.

  1. For Optimization configuration, choose Customize settings.
  2. For IAM role, choose the iceberg-optimizer-vpc-MyGlueTableOptimizerRole-xxx role created by the CloudFormation stack.
  3. For Virtual private cloud (VPC) – optional, choose myvpc_private_network_connection.

  1. Select I acknowledge that expired data will be deleted as part of the optimizers and choose Enable optimization.

Now the table optimizer has been configured with your VPC. After a while, you can see how the optimizer worked.

  1. Under Table optimization – new, choose View optimization history on the Actions menu.

You can confirm that the table optimizer worked successfully for this Iceberg table.

You have now seen how to set up the table optimizer with an AWS Glue network connection to run it through a specific VPC.

Clean up

When you have finished all the preceding steps, remember to clean up all the AWS resources you created using AWS CloudFormation:

  1. Delete the S3 bucket storing the Iceberg table and the AWS Glue job script.
  2. Delete the CloudFormation stack.

Conclusion

This post demonstrated how the Data Catalog supports automatic optimization of Iceberg tables through your VPC. With this enhancement, you can simplify table maintenance for your Iceberg tables under advanced security requirements. This feature is available today in all AWS Glue supported AWS Regions.

Try out this solution for your own use case, and share your feedback and questions in the comments.


About the Authors

Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his new road bike.

Paul Villena is an Analytics Solutions Architect in AWS with expertise in building modern data and analytics solutions to drive business value. He works with customers to help them harness the power of the cloud. His areas of interest are infrastructure as code, serverless technologies, and coding in Python.

Justin Lin is a software engineer on the AWS Lake Formation team. He works on delivering managed optimization solutions for open table formats to enhance customer data management and query performance. In his spare time, he enjoys playing tennis.

Himani Desai is a Software Engineer on the AWS Lake Formation team. She works on providing managed optimization solutions for Iceberg tables.

Abishek Shankar is a software engineer on the AWS Lake Formation team, working on providing managed optimization solutions for Iceberg tables.

Shyam Rathi is a Software Development Manager on the AWS Lake Formation team, working on delivering new features and enhancements related to modern data lakes.

Sandeep Adwankar is a Senior Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.


Appendix 1: Configure your S3 bucket to allow access only from a specific VPC

The instructions provided in this post help you configure your S3 bucket automatically through the CloudFormation template, but you can also manually configure your S3 bucket to allow access only from a specific VPC. This is an optional step to simulate the strict security regulation on your Iceberg table. Complete following steps:

  1. On the Amazon S3 console, choose Buckets in the navigation pane.
  2. Choose your S3 bucket.
  3. Choose Permissions.
  4. Under Bucket policy, choose Edit.
  5. Enter following bucket policy:
{
    "Version": "2012-10-17",
    "Id": "S3BucketPolicyVPCAccessOnly",
    "Statement": [
        {
            "Sid": "DenyIfNotFromAllowedVPC",
            "Effect": "Deny",
            "Principal": "*",
            "Action": [
                "s3:GetObject",
                "s3:ListBucket",
                "s3:PutObject"
            ],
            "Resource": [
                "arn:aws:s3:::<your-bucket-name>",
                "arn:aws:s3:::<your-bucket-name>/*"
            ],
            "Condition": {
                "StringNotEquals": {
                    "aws:SourceVpc": "<your-vpc-id>",
                    "aws:PrincipalArn": [
                        "arn:aws:iam::<your-account-id>:role/<your-IAM-role-name>"
                    ]
                }
            }
        }
    ]
}
  1. Choose Save changes.

Now this S3 bucket prevents any data operations not from the VPC. You can try uploading files to the bucket through Amazon S3 console to see that this operation fails as expected.

Appendix 2: Create an AWS Glue network connection

You can also can manually configure the AWS Glue network connection with the following steps:

  1. On the AWS Glue console, choose Data connections in the navigation pane.
  2. Under Connections, choose Create connection.
  3. Select Network, and choose Next.
  4. For VPC, choose your VPC created by the CloudFormation stack. The VPC ID is shown on the Outputs tab of the CloudFormation stack.
  5. For Subnet, choose your private subnet created by the CloudFormation stack. The subnet ID is shown on the Outputs tab of the CloudFormation stack.
  6. For Security groups, choose your security group created by the CloudFormation stack. The security group ID is shown on the Outputs tab of the CloudFormation stack.
  7. Choose Next.
  8. For Name, enter myvpc_private_network_connection.
  9. Choose Next.
  10. Review the configurations and choose Create connection.

Track performance of serverless applications built using AWS Lambda with Application Signals

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/track-performance-of-serverless-applications-built-using-aws-lambda-with-application-signals/

In November 2023, we announced Amazon CloudWatch Application Signals, an AWS built-in application performance monitoring (APM) solution, to solve the complexity associated with monitoring performance of distributed systems for applications hosted on Amazon EKS, Amazon ECS, and Amazon EC2. Application Signals automatically correlates telemetry across metrics, traces, and logs, to speed up troubleshooting and reduce application disruption. By providing an integrated experience for analyzing performance in the context of your applications, Application Signals gives you improved productivity focusing on the applications that support your most critical business functions.

Today we’re announcing the availability of Application Signals for AWS Lambda to eliminate the complexities of manual setup and performance issues required to assess application health for Lambda functions. With CloudWatch Application Signals for Lambda, you can now collect application golden metrics (the incoming and outgoing volume of requests, latency, faults, and errors).

AWS Lambda abstracts away the complexity of the underlying infrastructure, enabling you to focus on building your application without having to monitor server health. This allows you to shift your focus toward monitoring the performance and health of your applications, which is necessary to operate your applications at peak performance and availability. This requires deep visibility into performance insights such as volume of transactions, latency spikes, availability drops, and errors for your critical business operations and application programming interfaces (APIs).

Previously, you had to spend significant time correlating disjointed logs, metrics, and traces across multiple tools to establish the root cause of anomalies, increasing mean time to recovery (MTTR) and operational costs. Additionally, building your own APM solutions with custom code or manual instrumentation using open source (OSS) libraries was time-consuming, complex, operationally expensive, and often resulted in increased cold start times and deployment challenges when managing large fleets of Lambda functions. Now, you can use Application Signals to seamlessly monitor and troubleshoot health and performance issues in serverless applications, without requiring any manual instrumentation or code changes from your application developers.

How it works
Using the pre-built, standardized dashboards of Application Signals, you can identify the root cause of performance anomalies in just a few clicks by drilling down into performance metrics for critical business operations and APIs. This helps you visualize application topology which shows interactions between the function and its dependencies. In addition, you can define Service Level Objectives (SLOs) on your applications to monitor specific operations that matter most to you. An example of an SLO could be to set a goal that a webpage should render within 2000 ms 99.9 percent of the time in a rolling 28-day interval.

Application Signals auto-instruments your Lambda function using enhanced AWS Distro for OpenTelemetry (ADOT) libraries. This delivers better performance such as lower cold start latency,
memory consumption, and function invocation duration, so you can quickly monitor your applications.

I have an existing Lambda function appsignals1 and I will configure Application Signals in the Lambda Console to collect various telemetry on this application.

In the Configuration tab of the function I select Monitoring and operations tools to enable both the Application signals and the Lambda service traces.

I have an application myAppSignalsApp that has this Lambda function attached as a resource. I’ve defined an SLO for my application to monitor specific operations that matter most to me. I’ve defined a goal that states that the application executes within 10 ms 99.9 percent of the time in a rolling 1-day interval.

It can take 5-10 minutes for Application Signals to discover the function after it’s been invoked. As a result you’ll need to refresh the Services page before you can see the service.

Now I’m in the Services page and I can see a list of all my Lambda functions that have been discovered by Application Signals. Any telemetry that is emitted will be displayed here.

I can then visualize the complete application topology from the Service Map and quickly spot anomalies across my service’s individual operations and dependencies, using the newly collected metrics of volume of requests, latency, faults, and errors. To troubleshoot, I can click into any point in time for any application metric graph to discover correlated traces and logs related to that metric, to quickly identify if issues impacting end users are isolated to an individual task or deployment.

Available now
Amazon CloudWatch Application Signals for Lambda is now generally available and you can start using it today in all AWS Regions where Lambda and Application Signals are available. Today, Application Signals is available for Lambda functions that use Python and Node.js managed runtimes. We’ll continue to add support for other Lambda runtimes in near future.

To learn more, visit the AWS Lambda developer guide and Application Signals developer guide. You can submit your questions to AWS re:Post for Amazon CloudWatch, or through your usual AWS Support contacts.

– Veliswa.

Announcing a visual update to the AWS Management Console (preview)

Post Syndicated from Prasad Rao original https://aws.amazon.com/blogs/aws/announcing-a-visual-update-to-the-aws-management-console-preview/

Today, we are announcing a visual update to the AWS Management Console in preview. We are rolling out this update by using the latest version of Cloudscape, the Amazon Web Services (AWS) design system used to build intuitive, inclusive, and meaningful AWS experiences at scale.

In this post, I describe how the visual update makes it easier for you to scan content, focus on the key information, and find what you are looking for more effectively while preserving the familiar and consistent experience of the AWS Management Console.

AWS Management console home page - previous

AWS Management console home page - Visual Update

Improved readability
A revised typography scale and improved treatment of headings result in a stronger visual hierarchy, which helps you to better locate and understand your data. A refined use of color and weight across text elements help you differentiate key pieces of information faster. For example, you’ll see that labels in form fields are now more prominent, which eases scanning. The same applies to keys in key-value pairs and sections across components, such as service navigation, expandable elements, and tabs.

Cloudfront distribution console screenshot - Previous vs Visual Update

We improved the color palette, made it more vibrant, and simplified the color treatment of interactive elements. For example, secondary buttons, links, tokens, and interactive states for numerous interface elements are now blue, making it easier for you to interact with the content on the screen and contributing to improving task efficiency.

Screenshot showing improved color - Previous vs Visual Update

Improved focus in light and dark mode
Reduced visual complexity supports user focus. We replaced drop shadows with a new thinner stroke on main content wrappers, such as cards, panels, and containers, and unified the use of border styles across components. This reduces visual noise and optimizes the space inside the layout. Shadows are now reserved to add emphasis on specific interactive and transient elements, which helps simplify visual depth and improves the overall content hierarchy.

Screenshot showing improved focus - Previous vs Visual Update

We also released updates to dark mode to address the need for clearer differentiation between elements on the page. These changes include an update to the color ramp and improved contrast between interactive states across components.

Screenshot comparing dark mode of AWS Management Console home page - Previous vs Visual Update

Modernized interface
We modernized the interface while retaining familiarity to continue to offer predictable and recognizable experiences across AWS. The user experience is now easier on the eyes, thanks to the use of rounder shapes, brighter colors, and improved layout treatment. These updates create a smoother, more natural appearance, making the interface more visually pleasing.

To deliver a more delightful experience and support visual storytelling, we also introduced a whole new family of illustrations and motion while still offering the highest accessibility standards.

Example of an illustration introduced

Improved information density
We optimized information density by reducing unused space, leading to more content visible on the screen. Related data is now displayed closer together, reinforcing visual grouping. Space within content wrappers such as cards and containers has been minimized, so you can consume more information at once. The new layout is centered and wider, optimizing the experience to serve larger screen sizes than before. The visual update makes it easier to consume information, which creates a better and friendlier experience within the AWS Management Console.

Showing Improved information density on AWS Lambda Create Function Screen - Previous vs Visual Update

Showing Improved information density in tabular format - Previous vs Visual Update

Additionally, we introduced Toolbar, a new way to navigate and access contextual tools and features. This helps you perform your tasks while maximizing the amount of content available on screen.

Screenshot of toolbar introduced

Improved consistency
The interface is now more distinctive and consistent. Refreshed colors, iconography, and shapes help deliver a more dynamic and expressive experience while reinforcing a unified and cohesive journey across all AWS experiences.

Available now
You can start experiencing the visual update now in selected consoles across all AWS Regions by visiting the AWS Management Console. We’ll be extending the update across all services. Thanks to the new visual treatment, you can now benefit from an experience that’s more readable and intuitive and that contributes to improved overall task efficiency.

Introducing Amazon CloudFront VPC origins: Enhanced security and streamlined operations for your applications

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/introducing-amazon-cloudfront-vpc-origins-enhanced-security-and-streamlined-operations-for-your-applications/

I’m happy to introduce the release of Amazon CloudFront Virtual Private Cloud (VPC) origins, a new feature that enables content delivery from applications hosted in private subnets within their Amazon Virtual Private Cloud (Amazon VPC). This makes it easy to secure web applications, allowing you to focus on growing your businesses while improving security and maintaining high-performance and global scalability with CloudFront.

Customers serving content from Amazon Simple Storage Solution (Amazon S3), AWS Elemental Services and AWS Lambda Function URLs can use Origin Access Control as a managed solution to secure their origins, and make CloudFront the single front-door to your application. However, this was more difficult to achieve for applications that are hosted on Amazon Elastic Compute Cloud (Amazon EC2) or using load balancers, because you had to create your own solution to achieve the same result. You would have to use a combination of methods such as using access control lists (ACLs), managing firewall rules, or using logic such as header validation and a few other techniques to ensure that the endpoint remained exclusive to CloudFront.

CloudFront VPC origins removes the need for this kind of undifferentiated work by offering a managed solution that can be used to point CloudFront distributions directly to Application Load Balancers (ALBs), Network Load Balancers (NLBs), or EC2 instances inside your private subnets. This ensures that CloudFront becomes the sole ingress point for those resources with minimum configuration effort, providing you with improved performance and a cost-saving opportunity because it also eliminates the need for public IP addresses.

Configuring a CloudFront VPC origin
CloudFront VPC origins is available at no additional cost, making it an accessible option for all AWS customers. It can be integrated with new or existing CloudFront distributions using the Amazon CloudFront console or the AWS Command Line Interface (AWS CLI).

Imagine that you have an application hosted privately on an AWS Fargate for Amazon ECS fronted through an ALB. Let’s create a CloudFront distribution that uses the ALB directly inside the private subnet.

Start by navigating to the CloudFront console and select the new menu option: VPC origins.

vpc origins page

Creating a new VPC origin is straightforward. You only need to select from a few options. In the Origin ARN, you can search for available resources that are hosted in private subnets or enter it directly. You select the resources that you want, choose a friendly name for your VPC origin alongside some security options, and then confirm. Please note that, at launch, the VPC origin resource must be in the same AWS Account as the CloudFront distribution, although support for resources across all accounts is coming soon.

creating a vpc origin

After the creation process is complete, your VPC origin will be deployed and ready to go! You can check its status on the VPC origins page.

With this, we have created a CloudFront distribution that serves content directly from a resource hosted on a private subnet in a few clicks! After your VPC origin is created, you can navigate to your Distribution window, and add the VPC origin to your Distribution by either selecting the ARN from the dropdown or copy-pasting the ARN manually.

Remember, though, that it’s important to still continue to layer your application’s security by using services such as AWS Web Application Firewall (WAF) to protect from web exploits, or AWS Shield for managed DDos protection, and other services to achieve a full-spectrum protection.

Conclusion
CloudFront VPC Origins offers a new way for organizations to deliver secure, high-performance applications by enabling CloudFront distributions to serve content directly from resources hosted within private subnets. This reduces the complexity and cost of maintaining public-facing origins while ensuring that your application remains secure.

To learn more, see the getting started guide.

Matheus Guimaraes | @codingmatheus

Amazon CloudFront now accepts your applications’ gRPC calls

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-cloudfront-now-accepts-your-applications-grpc-calls/

Starting today, you can deploy Amazon CloudFront, our global content delivery network (CDN), in front of your gRPC API endpoints.

gRPC is a modern, efficient, and language-agnostic framework for building APIs. It uses Protocol Buffers (protobuf) as its interface definition language (IDL), which enable you to define services and message types in a platform-independent manner. With gRPC, communication between services is achieved through lightweight and high-performance remote procedure calls (RPCs) over HTTP/2. This promotes efficient and low-latency communication across services, making it ideal for microservices architectures.

gRPC offers features such as bidirectional streaming, flow control, and automatic code generation for a variety of programming languages. It’s well-suited for scenarios in which you require high performance, efficient communication, and real-time data streaming. If your application needs to handle a large amount of data or requires low-latency communication between client and server, gRPC can be a good choice. However, gRPC might be more challenging to learn compared to REST. For example, gRPC relies on the protobuf serialization format, which requires developers to define their data structures and service methods in .proto files.

I see two benefits of deploying CloudFront in front of your gRPC API endpoints.

First, it allows the reduction of latency between the client application and your API implementation. CloudFront offers a global network of over 600+ edge locations with intelligent routing to the closest edge. Edge locations provide TLS termination and optional caching for your static content. CloudFront transfers client application requests to your gRPC origin through the fully managed, low-latency, and high-bandwidth private AWS network.

Secondly, your applications benefit from additional security services deployed on edge locations, such as traffic encryption, the validation of the HTTP headers through AWS Web Application Firewall, and AWS Shield Standard protection against distributed denial of service (DDoS) attacks.

Let’s see it in action
To start this demo, I use the gRPC route-guide demo from the official gRPC code repository. I deploy this example application in a container for ease of deployment (but any other deployment option is supported too).

I use this Dockerfile

FROM python:3.7
RUN pip install protobuf grpcio
COPY ./grpc/examples/python/route_guide .
CMD python route_guide_server.py
EXPOSE 50051

I also use the AWS Copilot command line to deploy my container on Amazon Elastic Container Service (Amazon ECS). The Copilot command prompts me to collect the information it requires to build and deploy the container. Then, it creates the ECS cluster, the ECS service, and the ECS task automatically. It also creates a TLS certificate and the load balancer for me. I test the client application by modifying line 122 to use the DNS name of the load balancer listener endpoint. I also change the client application code to use grpc.secure_channel instead of grpc.insecure_channel because the load balancer provides the application with an HTTPS endpoint.

gRPC client application demo - source code with ALB

When I’m confident my API is correctly deployed and working, I proceed and configure CloudFront.

First, in the CloudFront section of the AWS Management Console, I select Create distribution.

Under Origin, I enter my gRPC endpoint DNS name as Origin domain. I enable HTTPS only as Protocol and leave the HTTPS port as is (443). Then I choose a Name for the distribution.

CloudFront - Add origin and name

Under Viewer, I select HTTPS only as Viewer protocol policy. Then, I select GET, HEAD, OPTIONS, PUT, POST, PATCH, DELETE as Allowed HTTP methods. I select Enable for Allow gRPC requests over HTTP/2.

CloudFront - Viewer Policy

Under Cache key and origin requests, I select AllViewer as Origin request policy.

The default cache policy is CacheOptimized, but gRPC isn’t cacheable API traffic. Therefore, I select CachingDisabled as Cache policy.

CloudFront - Cache policy

AWS WAF helps protect you against common web exploits and bots that can affect availability, compromise security, or consume excessive resources. For gRPC traffic, AWS WAF can inspect the HTTP headers of the request and enforce access control. It doesn’t inspect the request body in protobuf format.

For this demo, I choose to not use AWS WAF. Under Web Application Firewall (WAF), I select Do not enable security protections.

CloudFront - Security

I also keep all the other options with their default value. HTTP/2 support is selected by default. Do not disable it because it is required for gRPC.

Finally, I select Create distribution.

CloudFront - Create distribution

There is only one switch to enable gRPC on top of the usual setup. When turned on, with HTTP/2 and HTTP POST enabled, CloudFront detects gRPC client traffic and forwards it to your gRPC origin.

After a few minutes, the distribution is ready. I copy and paste the endpoint URL of the CloudFront distribution, and I change the client-side app to make it point to CloudFront instead of the previously created load balancer.

gRPC client application demo - source code

I test the application again, and it works.

gRPC client application demo - execution

Pricing and Availability
gRPC origins are available on all the more than 600 CloudFront edge locations at no additional cost. The usual requests and data transfer fees apply.

Go and point your CloudFront origin to a gRPC endpoint today.

— seb

Enhance data governance with enforced metadata rules in Amazon DataZone

Post Syndicated from Ramesh H Singh original https://aws.amazon.com/blogs/big-data/enhance-data-governance-with-enforced-metadata-rules-in-amazon-datazone/

We’re excited to announce a new feature in Amazon DataZone that offers enhanced metadata governance for your subscription approval process. With this update, domain owners can define and enforce metadata requirements for data consumers when they request access to data assets. By making it mandatory for data consumers to provide specific metadata, domain owners can achieve compliance, meet organizational standards, and support audit and reporting needs.

Many organizations require additional metadata from data consumers during the subscription request process to align with internal workflows and regulatory requirements. With enforced metadata rules, domain unit owners can establish consistent governance practices across all data subscriptions. For example, financial services organizations can mandate specific compliance-related metadata when data consumers request access to sensitive financial data. Similarly, healthcare providers can enforce metadata requirements to align with regulatory standards for patient data access. This feature simplifies the approval process by guiding data consumers through completing mandatory fields and enabling data owners to make informed decisions, ensuring data access requests meet organizational policies.

By streamlining metadata governance, Amazon DataZone empowers customers to meet compliance standards, maintain audit readiness, and simplify access workflows for enhanced efficiency and control. For example, one of our customers, Bristol Myers Squibb (BMS), leverages Amazon DataZone to address their specific data governance needs. Sitikantha Sarangi, Director of Data Engineering and ML Ops Platform at BMS, says:

“At BMS, our teams have been leveraging Amazon DataZone’s comprehensive data governance solution to catalog and enable secure data subscriptions across the organization within governed project environments. With the new custom metadata enforcement feature, we now can more easily navigate our data catalog. This capability allows us to set specific requirements for data consumers, such as providing a compliance certification link or detailing data usage intentions, ensuring that access requests for sensitive data are thoroughly reviewed and approved in alignment with our standards. This customization helps us more efficiently ensure we are appropriately utilizing data while facilitating efficient, secure data sharing across teams.” 

Key benefits

The feature benefits multiple stakeholders. Domain unit owners can ensure compliance by enforcing metadata requirements, granting access only after thorough reviews. Data consumers benefit from a streamlined subscription request process, guided by metadata requirements that reduce complexity. Data producers gain clarity with detailed subscription requests, enabling informed decisions aligned with required standards. Overall, the key benefits are:

  • Enhanced control for domain owners – Admins and domain unit owners can now enforce additional metadata requirements on subscription requests, making sure that data consumers supply essential information for thorough review and compliance checks
  • Custom workflow support – Organizations can build custom workflows for assets by capturing critical metadata from data consumers, such as AWS account IDs or project-specific identifiers, to fulfill access requests

In this post, we walk you through setting up and using metadata enforcement to create seamless, compliant data access workflows.

Solution overview

The solution in this post is composed of two parts. In the first part, we walk through the steps necessary to enforce metadata for subscription requests for managed assets. In the second part, we walk through the steps necessary to request subscriptions for custom assets.

Prerequisites

To follow this post, user should already have Amazon DataZone setup with respective projects to publish and consume the assets. The publisher of the Retail project must have published a shipments data asset in Amazon DataZone. The domain owner or admin must have created a metadata form required for the subscription request.

This feature also supports metadata enforcement for subscription requests of a data product. For instructions on how to set this up, refer to Amazon DataZone data products.

Solution walkthrough: Enhance data governance with enforced metadata rules for Managed Assets

To perform the solution in this post, follow the steps in the next sections.

Metadata enforcement for subscription requests

To enforce metadata for subscription requests, use the following steps.

Step 1: Domain owner configures metadata requirements

Domain unit owners can configure metadata enforcement in Amazon DataZone as follows:

  1. On the Amazon DataZone console, choose Domain to open your domain or domain unit settings.
  2. Choose dataplatform, as shown in the following screenshot.
  3. To add metadata forms for subscription requests, on the RULES tab, choose ADD, as shown in the following screenshot.
  4. Provide the name to the metadata form rule.
  5. Choose ADD ANOTHER METADATA FORM.
  6. Choose from a list of available metadata forms within the domain or domain unit. Search options make navigation straightforward.

You can select multiple forms for enforcement on subscription requests.

  1. Choose Add, as shown in the following screenshot.

Create metadata form rule as below:

  1. In the next screen, you can specify additional settings. You can apply metadata forms across all asset types or limit them to specific asset types. Additionally, choose whether the rule applies to a specific project or all projects within the domain. After the scope is defined as shown in the screenshot, choose ADD RULE.

    Note: Enable metadata enforcement across child domains, with optional permissions allowing child domains to override the parent domain’s enforced forms. This option is available while defining the scope, if the domain owner chooses All projects, as shown in the following screenshot.

Step 2: Data consumer submits subscription request

After metadata enforcement is configured, data consumers follow these steps to request access:

  1. To find and select an asset in the Amazon DataZone catalog, choose MARKETING and then sign in to the Amazon DataZone console as a data consumer. On the search bar, enter the shipments data asset, as shown in following screenshot.
  2. Choose SUBSCRIBE to open the subscription request modal, as shown in the following screenshot.
  3. Choose a project and provide a Reason for request, as shown in the following screenshot.
  4. Fill in the required metadata fields as specified by the domain unit. If mandatory fields are incomplete, they will be highlighted, and the submission will be disabled until resolved. After all the mandatory fields are entered, choose APPLY, as shown in the following screenshot.
  5. Choose Request to submit the subscription request, as shown in the following screenshot.

After submitting, an event is generated in Amazon EventBridge, which can be used in custom workflows outside of Amazon DataZone as needed.

Step 3: Data producer (owner) approves the subscription

After a data consumer submits a subscription request, they review the metadata. The data producer receives the subscription request with all metadata provided by the data consumer.

  1. Sign in to the Amazon DataZone console as a data producer. Choose RETAIL as the
  2. In the navigation pane, choose Incoming requests and find the subscription request. Choose View request, as shown in the following screenshot.
  3. Data producers can review the metadata, including document links and account IDs, to determine if the request meets compliance and workflow requirements before granting access, as shown in the following screenshot.
  4. Under Approval access, choose Full access to provide full access to data. For fine-grain access control, choose Approve with row or column filters. For this post, we choose Full access.
  5. Provide the Decision comment.
  6. Choose APPROVE, as shown in the following screenshot.

Step 4: Data consumer consumes the data

Now, data consumers follow these steps:

  1. After the subscription grants are approved and fulfilled, sign in to the Amazon DataZone console as data consumer from MARKETING project to query the subscribed data.
  2. Choose MARKETING On the Environments tab, choose Query data through Amazon Athena, as shown in the following screenshot.
  3. Query the subscribed data asset shipments in Amazon Athena, with below query and as shown in the screenshot.
    SELECT * from “env_mkt_datalake_sub_db”.“shipments” limit 10;

Solution walkthrough: Enhance data governance with enforced metadata rules for Custom Assets

Customers can manage access grants for unmanaged assets using Amazon DataZone. When a subscription to an asset in the business data catalog is approved by the data owner, Amazon DataZone publishes an event in Amazon EventBridge in the account along with all the necessary information in the payload that you can use to create the access grants between the source and the target. Using metadata enforcement for unmanaged assets, customers can provide all context in the single request.

STEP 1: Create a custom asset type

To create a custom asset type Metrics with an attached metadata form to describe the metric asset type, follow these steps:

Below is an example of a custom asset type – “Metrics” which has two fields 1/Dashboard Link and 2/Calculation

Step 2: Data producer creates a custom asset using the “Metrics” asset type

The data producer creates a Conversion Rate Metric with all metadata along with associated metadata forms by following these steps:

Below is “Conversion Rate Metric” asset created in DataZone. The highlighted boxes show that is an Unmanaged asset and of type “Metrics” that was created in the previous step.

Step 3: Domain owner configures metadata requirements

Domain unit owners can configure metadata enforcement in Amazon DataZone as follows:

  1. On the Amazon DataZone console, choose Domain to open your domain or domain unit settings.
  2. To add metadata forms for subscription requests, on the RULES tab, choose ADD, as shown in the following screenshot.
  3. To select metadata forms, provide the Name to the metadata form rule.
  4. Choose ADD METADATA FORM, as shown in the following screenshot.
  5. Remaining fields can be left as default. For this blog, please set it as shown in below
  6. In the Add metadata form pop-up, enter MetricsRequestForm, as shown in the following screenshot.

  7. Choose ADD Rule as shown above to create the rule for all metrics assets. Below is the screenshot of the rule once created.

Step 4: Admins sets up an EventBridge rule

To set up an EventBridge rule, follow these steps:

  1. Create an EventBridge rule to capture all new subscription requests. Please see the documentation Amazon DataZone events and notifications for details to setup.
  2. Create an AWS Lambda function as a target to action on the event. Please see documentation – Event bus targets in Amazon EventBridge to setup targets.

For this blog, set the below event pattern that triggers the lambda only for new Subscription requests.

{
  "source": ["aws.datazone"],
  "detail-type": ["Subscription Request Created"]
}

Step 5: Data consumer submits subscription request

After metadata enforcement is configured, data consumers follow these steps to request access:

  1. To locate the asset in the Amazon DataZone catalog, sign in to the Amazon DataZone console as a data consumer from the marketing Use the search bar to find the Conversion Rate Metric asset. Choose SUBSCRIBE, as shown in the following screenshot.
  2. Provide details, including the Metrics Request Form associated with the Metrics asset type.
  3. Choose REQUEST, as shown in the following screenshot.

You will receive notification confirming that your subscription request is submitted, as shown in the following screenshot.

For the request, EventBridge will capture the following request event and send it to the setup target:

{
    'version': '0',
    'id': '3fdf59a2-f95c-192f-0901-4025dc6e6a61',
    'detail-type': 'Subscription Request Created',
    'source': 'aws.datazone',
    'account': '1234567890', 
    'time': '2024-11-15T18:57:16Z', 
    'region': 'us-east-1', 
    'resources': [], 
    'detail': 
        {
            'version': '283',
            'internal': None,
            'metadata': 
                {'
                    id': 'cwaxxxlj', 
                    'version': '1',
                    'typeName': 'SubscriptionRequestEntityType',
                    'domain': 'dzd_xxxxxxxxx1z',
                    'user': 'd1xxxxx-eexxx-xxxx-axxxx-0xxxxxxxx8ce',
                    'awsAccountId': '1234567890', 
                    'owningProjectId': '555xxxxxxrmv', 
                    'clientToken': '3bxxxxxxxxxxc91bb76d6'
                }, 
            'data': 
                {
                    'autoApproved': False, 
                    'requesterId': 'd1xxxxx848ce',
                    'reviewerId': '54uxxxxxxd3',
                    'status': 'PENDING',
                    'subscribedListings': [{'id': '6ixxgev', 'item': {'assetListing': {'entityId': 'xxxxxxxxx7', 'entityType': 'Metrics'}}, 'ownerProjectId': '5xxxxxx3', 'version': '2'}], 
                    'subscribedPrincipals': [{'id': '555xxxxxxrmv', 'type': 'PROJECT'}]
                }
            }
}

The data steward and asset owner can get details for the request with the  GetSubscriptionRequestDetails API and view the asset details and form associated with the request:

{
    "id": "cwxxxlj",
    "createdBy": "d17xxxxxxx848ce",
    "domainId": "dzd_xxxxxxz",
    "status": "PENDING",
    "createdAt": "2024-11-15T20:26:01.014000+00:00",
    "updatedAt": "2024-11-15T20:26:01.014000+00:00",
    "requestReason": "Marketing Analytics use case",
    "subscribedPrincipals": [
        {
            "project": {
                "id": "bxxxxx23hj",
                "name": "Marketing"
            }
        }
    ],
    "subscribedListings": [
        {
            "id": "6xxxxxxx1ev",
            "revision": "2",
            "name": "Conversion Rate Metric",
            "description": "Conversion rate calculates the percentage of web visitors who complete a desired action, such as creating an account, placing an order or clicking a link",
            "item": {
                "assetListing": {
                    "entityId": "b8xxxxxd7",
                    "entityRevision": "7",
                    "entityType": "Metrics",
                    "forms": "{\n  \"DZ_Internal_Basic_Form\" : {\n    \"name\" : \"Conversion Rate Metric\",\n    \"description\" : \"Conversion rate calculates the percentage of web visitors who complete a desired action, such as creating an account, placing an order or clicking a link\"\n  },\n  \"amazonstatus\" : {\n    \"publishingPrecedence\" : \"PUBLISHED_INDIVIDUALLY\",\n    \"status\" : \"ACTIVE\"\n  },\n  \"AssetCommonDetailsForm\" : {\n    \"readMe\" : \"Conversion Rate is a key performance metric used in marketing, e-commerce, and digital analytics. It measures the percentage of users or visitors who take a desired action out of the total number of users or visitors. This desired action, known as a \\\"conversion,\\\" can vary depending on the specific goals of a business or campaign.\\n\\n\\nApplications:\\n\\n- E-commerce: Percentage of website visitors who make a purchase\\n- Marketing: Percentage of leads who become customers\\n- Digital Advertising: Percentage of ad viewers who click on an ad or complete a form\\n- Email Marketing: Percentage of email recipients who click a link or perform a desired action\\n\\n\\nImportance:\\n\\n- Measures effectiveness of marketing efforts and user experience\\n- Helps in understanding customer behavior and preferences\\n- Guides optimization efforts for websites, ads, and marketing campaigns\\n- Often used as a key metric for ROI (Return on Investment) calculations\"\n  },\n  \"MarketingMetrics\" : {\n    \"DashboardLink\" : \"www.anycompany.com/marketing/conversion_rate\",\n    \"Calculation\" : \"Conversion rate = Conversions / Total visitors x 100\"\n  },\n  \"amazonmetadata\" : {\n    \"entityVersion\" : \"7\",\n    \"createdAt\" : \"2024-11-15T16:43:15.325935428Z\",\n    \"typeNamespace\" : \"dzd_6xxxxxx1z\",\n    \"sourceCategory\" : \"asset\",\n    \"typeName\" : \"Metrics\",\n    \"entityId\" : \"byxxxxxdolk7\",\n    \"sourceEntityFormDetails\" : [ {\n      \"typeNamespace\" : \"dzd_xxxxx1z\",\n      \"typeVersion\" : \"15\",\n      \"formName\" : \"MarketingMetrics\",\n      \"typeName\" : \"MarketingMetrics\"\n    }, {\n      \"typeNamespace\" : \"amazon.datazone\",\n      \"typeVersion\" : \"10\",\n      \"formName\" : \"DZ_Internal_Basic_Form\",\n      \"typeName\" : \"NamedDataZoneBasicFormType\"\n    }, {\n      \"typeNamespace\" : \"amazon.datazone\",\n      \"typeVersion\" : \"6\",\n      \"formName\" : \"AssetCommonDetailsForm\",\n      \"typeName\" : \"AssetCommonDetailsFormType\"\n    }, {\n      \"typeNamespace\" : \"amazon.datazone.internal\",\n      \"typeVersion\" : \"1\",\n      \"formName\" : \"DZ_Internal_Rendering_Config_Form\",\n      \"typeName\" : \"RenderingConfigFormType\"\n    } ]\n  },\n  \"DZ_Internal_Rendering_Config_Form\" : {\n    \"metadataFormItems\" : [ {\n      \"formName\" : \"MarketingMetrics\",\n      \"collapse\" : false\n    }, {\n      \"formName\" : \"AssetCommonDetailsForm\",\n      \"collapse\" : false\n    } ]\n  }\n}",
                    "glossaryTerms": []
                }
            },
            "ownerProjectId": "54xxxxxd3",
            "ownerProjectName": "Custom-Metrics-Assets"
        }
    ],
    "metadataForms": [
        {
            "formName": "MetricsRequestForm",
            "typeName": "MetricsRequestForm",
            "typeRevision": "5",
            "content": "{\"BusinessUnit\": \"AWS\",\"ContactEmail\": \"[email protected]\",\"Team\": \"DataZone\"}"
        }
    ]
}

The data and asset owner can use these details to orchestrate an approval workflow using the Lambda function. After it has been validated, the asset owner or steward can then call the AcceptSubscriptionRequest API to grant access. The data consumer will be notified after access is approved. The following screenshot shows the notification that the subscription was approved.

Now that the subscription is approved, users can use the dashboard URL to access the metric.

Cleanup

To make sure no additional charges are incurred after testing, delete the Amazon DataZone domain. Refer to Delete Amazon DataZone domains for the process.

Conclusion

The new metadata enforcement rule for subscription requests in Amazon DataZone strengthens data governance by empowering domain unit owners to establish clear metadata requirements for data consumers, streamlining access requests and enhancing data governance. This feature enables organizations to align with the organization’s metadata standards, implement custom workflows, and provide a consistent, governed data access experience.

The feature is supported in all AWS Regions where Amazon DataZone is available at the time of this writing. To check which Regions are available, refer to AWS Services by Region. Check out the video below to learn more about how to set up metadata rules for subscription workflows. Get started with the technical documentation.


About the Authors

Ramesh H Singh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon DataZone team. He is passionate about building high-performance ML/AI and analytics products that enable enterprise customers to achieve their critical goals using cutting-edge technology. Connect with him on LinkedIn.

Pradeep Misra PicPradeep Misra is a Principal Analytics Solutions Architect at AWS. He works across Amazon to architect and design modern distributed analytics and AI/ML platform solutions. He is passionate about solving customer challenges using data, analytics, and AI/ML. Outside of work, Pradeep likes exploring new places, trying new cuisines, and playing board games with his family. He also likes doing science experiments, building LEGOs and watching anime with his daughters.

Lakshmi Nair is a Senior Analytics Specialist Solutions Architect at AWS. She specializes in designing advanced analytics systems across industries. She focuses on crafting cloud-based data platforms, enabling real-time streaming, big data processing, and robust data governance.

Santhosh Padmanabhan is a Software Development Manager at AWS, leading the Amazon DataZone engineering team. His team designs, builds, and operates services specializing in data, machine learning, and AI governance. With deep expertise in building distributed data systems at scale, Santhosh plays a key role in advancing AWS’s data governance capabilities.

Expanded resource awareness in Amazon Q Developer

Post Syndicated from Brendan Jenkins original https://aws.amazon.com/blogs/devops/expanded-resource-awareness-in-amazon-q-developer/

Recently, Amazon Q Developer announced expanded support for account resource awareness with Amazon Q in the AWS Management Console along with the general availability of Amazon Q Developer in AWS Chatbot, enabling you to ask questions from Microsoft Teams or Slack. Additionally, Amazon Q will now provide context-aware assistance for your questions about resources in your account depending on where you are in the console. Amazon Q in the console gives you the ability to use natural language with the Amazon Q Developer chat capability to list resources in your AWS account, get specific resource details, and ask about related resources, launched in preview on April 30, 2024.

In this blog, I will highlight the new expanded functionality of this feature in Amazon Q Developer including understanding relationships between account resources, context-awareness, and the general availability of the AWS Chatbot integration with Microsoft Teams and Slack.

Expanded account resource awareness with Amazon Q Developer

Prior to the launch of the expanded support, you could ask Amazon Q Developer to list resources in your AWS Account with prompts such as “List all my EC2 instances in us-east-1” and the service would list all your Amazon Elastic Compute Cloud (Amazon EC2) instances. Now, with the expanded support, you can ask more complex questions about your AWS account resources. I will show a few examples in this section of this post.

For our first example, imagine that you’re a developer who is responsible for maintaining code as a part of the software development lifecycle (SDLC) and you frequently use AWS Lambda for development and Amazon Relational Database Service (RDS) in the backend as a part of your development process. With this new update, a developer could open a new Q chat in the AWS Management Console, and enter a prompt such as: “Which RDS clusters are due for an update?”

User entering prompt Amazon Q Developer chat in the AWS management console about listing all RDS clusters that need updates in their account and Amazon Q listing those Databases.

Figure 1: Amazon Q Developer listing RDS clusters needing an update

As a result, the Amazon Q Developer console chat will return a list of all your Amazon RDS clusters that have available updates as shown in Figure 1 above.

Now, for another example, you want to update any Lambda functions in your AWS account that had a Simple Notification Service (SNS) topic as a trigger due to moving to a new SNS topic you recently created. To identify which SNS topics are still being used, you could enter a prompt such as “List all the SNS topics that trigger a lambda function.”

User entering prompt Amazon Q Developer chat in the AWS management console about listing all SNS topics that trigger a lambda function and Amazon Q listing the SNS topics as an output.

Figure 2: Amazon Q listing SNS topics that are lambda triggers

As shown in the prior example, Amazon Q Developer was able to identify any SNS topics in the form of Amazon resource name (ARN) that was set to trigger a lambda function in the AWS account as intended.

Additionally, you can ask a follow up question in the same chat to investigate more. You can send a prompt such as “Which lambda function uses the arn:aws:sns:us-east-1:76859XXXX:FailoverHealthcheck SNS topic?”

User entering prompting Amazon Q Developer chat with a follow up question in the AWS management console about which Lambda is associated with an SNS topic.

Figure 3: Asking Q Developer a follow up question about a resource

From Figure 3 above, you can see that there is a Lambda function/endpoint associated with the SNS topic resource that Amazon Q Developer was able to identify.

Outside of the examples above, here are some other prompts/examples that can be explored for the expanded support:

– “Do I have any ECS clusters with pending tasks?”

– “Are there any ECS clusters in my account with services in DRAINING status?”

Amazon Q Developer understands where you are in the console

Amazon Q Developer in the AWS Management Console now provides context-aware assistance for your questions about resources in your account. This feature allows you to ask questions directly related to the console page you’re viewing, eliminating the need to specify the service or resource in your query. Q Developer uses the current page as additional context to provide more accurate and relevant responses, streamlining your interaction with AWS services and resources.

Prior to the update, a user would have to prompt, “What is the public IPv4 address of my instance i-08ccXXXXXX?”  Now, if you are viewing an EC2 instance in the console and prompt Amazon Q, “What is the public IPv4 address of my instance?” you will not need to specify the instance you are referring to.

User entering prompt Amazon Q Developer chat in the AWS management console about what the IP address is of the instance on the page.

Figure 4: Asking Amazon Q about an EC2 instance being viewed

In figure 4 above, Amazon Q’s console chat was able to use its context-awareness to pick up on what the IPv4 address was on the console page where I was currently working, despite me not specifying which instance I was referring to.

AWS ChatBot can now answer questions about AWS resources in Microsoft Teams and Slack

Recently, we announced the general availability of Amazon Q Developer in AWS Chatbot, which provides answers to customers’ AWS resource related queries in Microsoft Teams and Slack. This gives teams the ability to quickly find relevant resources to troubleshoot issues using natural language queries in the chat channels of Microsoft Teams or Slack.

For example, you could integrate the AWS Chatbot Service with Amazon Q Developer to allow you to enter a prompt in Slack such as “@aws show EC2 instances in running state in us-east-1”.

User entering prompt in slack to ask the AWS Chatbot about EC2 resources and Amazon Q responding

Figure 5: Amazon Q listing all EC2 resources in Slack

As shown in figure 5 above, Amazon Q was able to list all the EC2 resources and place them into a slack channel showing an example of the functionality in action.

Conclusion

Amazon Q Developer has enhanced its cloud resource management capabilities, enabling more intuitive and intelligent interactions with AWS resources. The new features allow developers to ask complex, context-aware questions about their cloud infrastructure directly through the AWS Management Console, Microsoft Teams, and Slack. Users can now easily discover new details about specific resources with natural language queries that provide precise, contextual information. These improvements represent a significant step forward in simplifying cloud resource management, making it faster and more user-friendly for development teams to understand, track, and maintain their AWS environments. To learn more about chatting with your AWS resources, check out Console documentation and AWS Chatbot documentation.

About the authors

Brendan Jenkins

Brendan Jenkins is a Tech Lead Solutions Architect at Amazon Web Services (AWS) working with Enterprise AWS customers providing them with technical guidance and helping achieve their business goals. He has an area of specialization in DevOps and Machine Learning technology.

Introducing Point in Time queries and SQL/PPL support in Amazon OpenSearch Serverless

Post Syndicated from Jagadish Kumar original https://aws.amazon.com/blogs/big-data/introducing-point-in-time-queries-and-sql-ppl-support-in-amazon-opensearch-serverless/

Today we announced support for three new features for Amazon OpenSearch Serverless: Point in Time (PIT) search, which enables you to maintain stable sorting for deep pagination in the presence of updates, and Piped Processing Language (PPL) and Structured Query Language (SQL), which give you new ways to query your data. Querying with SQL or PPL is useful if you’re already familiar with the language or want to integrate your domain with an application that uses them.

OpenSearch Serverless is a powerful and scalable search and analytics engine that enables you to store, search, and analyze large volumes of data while reducing the burden of manual infrastructure provisioning and scaling as you ingest, analyze, and visualize your time series and search data, simplifying data management and enabling you to derive actionable insights from data. The vector engine for OpenSearch Serverless also makes it easy for you to build modern machine learning (ML) augmented search experiences and generative artificial intelligence (generative AI) applications without needing to manage the underlying vector database infrastructure.

PIT search

Point in Time (PIT) search lets you run different queries against a dataset that’s fixed in time. Typically, when you run the same query on the same index at different points in time, you receive different results because documents are constantly indexed, updated, and deleted. With PIT, you can query against a state of your dataset for a point in time. Although OpenSearch still supports other ways of paginating results, PIT search provides superior capabilities and performance because it isn’t bound to a query and supports consistent pagination. When you create a PIT for a set of indexes, OpenSearch creates contexts to access data at that point in time and when you use a query with a PIT ID, it searches the contexts that are frozen in time to provide consistent results.

Using PIT involves the following high-level steps:

  1. Create a PIT.
  2. Run search queries with a PIT ID and use the search_after parameter for the next page of results.
  3. Close the PIT.

Create a PIT

When you create a PIT, OpenSearch Serverless provides a PIT ID, which you can use to run multiple queries on the frozen dataset. Even though the indexes continue to ingest data and modify or delete documents, the PIT references the data that hasn’t changed since the PIT creation.

Run a search query with the PIT ID

PIT search isn’t bound to a query, so you can run different queries on the same dataset, which is frozen in time.

When you run a query with a PIT ID, you can use the search_after parameter to retrieve the next page of results. This gives you control over the order of documents in the pages of results.

The following response contains the first 100 documents that match the query. To get the next set of documents, you can run the same query with the last document’s sort values as the search_after parameter, keeping the same sort and pit.id. You can use the optional keep_alive parameter to extend the PIT time.

Close the PIT

When your queries on the dataset are complete, you can delete the PIT using the DELETE operation. PITs automatically expire after the keep_alive duration.

Considerations and limitations

Keep in mind the following limitations when using this feature:

SQL and PPL support

OpenSearch Serverless provides a primary query interface called query DSL that you can use to search your data. Query DSL is a flexible language with a JSON interface. In addition to DSL, you can now extract insights out of OpenSearch Serverless using the familiar SQL query syntax.

You can use the SQL and PPL API, the /plugins/_sql and /plugins/_ppl endpoints respectively, to search the data. You can use aggregations, group by, and where clauses to investigate your data and read your data as JSON documents or CSV tables, so you have the flexibility to use the format that works best for you. By default, queries return data in JDBC format. You can specify the response format as JDBC, standard OpenSearch JSON, CSV, or raw.

Use the /plugins/_sql endpoint to send SQL queries to the SQL plugin, as shown in the following example.

Besides basic filtering and aggregation, OpenSearch SQL also supports complex queries, such as querying semi-structured data, set operations, sub-queries and limited JOINs. Beyond the standard functions, OpenSearch functions are provided for better analytics and visualization.

For PPL queries, use the /plugins/_ppl endpoint to send queries to the SQL plugin.

Considerations and limitations

Keep in mind the following:

  • Query Workbench is not supported for SQL and PPL queries
  • The SQL and PPL CLI is supported and can be used to issue SQL and PPL queries
  • DELETE statements are not supported
  • SQL plugin data sources are not supported
  • The SQL query stats API is not supported

Summary

In this post, we discussed new features in OpenSearch Serverless. PIT is a useful feature when you need to maintain a consistent view of your data for pagination during search operations. SQL in OpenSearch Service bridges the gap between traditional relational database concepts and the flexibility of OpenSearch’s document-oriented data storage. You can send SQL and PPL queries to the _sql and _ppl endpoints, respectively, and use aggregations, group by, and where clauses to analyze their data.

For more information, refer to :


About the Authors

Jagadish Kumar (Jag) is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service. He is deeply passionate about Data Architecture and helps customers build analytics solutions at scale on AWS.

Frank Dattalo is a Software Engineer with Amazon OpenSearch Service. He focuses on the search and plugin experience in Amazon OpenSearch Serverless. He has an extensive background in search, data ingestion, and AI/ML. In his free time, he likes to explore Seattle’s coffee landscape.

Milav Shah is an Engineering Leader with Amazon OpenSearch Service. He focuses on the search experience for OpenSearch customers. He has extensive experience building highly scalable solutions in databases, real-time streaming, and distributed computing. He also possesses functional domain expertise in verticals like Internet of Things, fraud protection, gaming, and ML/AI. In his free time, he likes to ride his bicycle, hike, and play chess.

Introducing Amazon MWAA micro environments for Apache Airflow

Post Syndicated from Hernan Garcia original https://aws.amazon.com/blogs/big-data/introducing-amazon-mwaa-micro-environments-for-apache-airflow/

Amazon Managed Workflows for Apache Airflow (Amazon MWAA), is a managed Apache Airflow service used to extract business insights across an organization by combining, enriching, and transforming data through a series of tasks called a workflow. It enhances infrastructure security and availability while reducing operational overhead.

Today, we’re excited to announce mw1.micro, the latest addition to Amazon MWAA environment classes. This offering is designed to provide an even more cost-effective solution for running Airflow environments in the cloud. With mw1.micro, we’re bringing the power of Amazon MWAA to teams who require a lightweight environment without compromising on essential features. In this post, we’ll explore mw1.micro characteristics, key benefits, ideal use cases, and how you can set up an Amazon MWAA environment based on this new environment class.

Customers maintain multiple MWAA environments to separate development stages, optimize resources, manage versions, enhance security, ensure redundancy, customize settings, improve scalability, and facilitate experimentation. This approach offers greater flexibility and control over workflow management. These organizations often maintain multiple AWS accounts for development, testing, and production stages, leading to increased complexity and cost. The traditional approach of using full-sized Amazon MWAA environments for development and testing can also be expensive, especially for teams working on smaller projects or proof-of-concept initiatives. Additionally, customers adopting a federated deployment model find it challenging to provide isolated environments for different teams or departments, and at the same time optimize cost. The introduction of mw1.micro addresses these pain points by offering an option that enables a more efficient resource utilization and significant cost savings.

The micro environment class

The mw1.micro configuration provides a balanced set of resources suitable for small-scale data processing and orchestration tasks. The class allocates 1 vCPU and 3GB of RAM for a scheduler/worker hybrid container. Similarly, the web server is equipped with 1 vCPU and 3 GB RAM configuration. The Amazon Elastic Container Service (Amazon ECS) tasks launched in the environment use AWS Fargate platform version 1.4.0, increasing ephemeral task storage to 20 GB.

mw1.micro environments support up to three concurrent tasks, making it ideal for sequential or lightly parallelized workflows. Additionally, it can accommodate up to 25 DAGs, providing ample capacity for organizing and managing various data pipelines and processes. This micro environment is particularly well-suited for development, testing, or small production workloads where resource optimization and cost-efficiency are primary concerns.

The following table summarizes the environment capabilities of mw1.micro.

Class/Resources Scheduler and Worker vCPU/RAM Web Server vCPU/RAM Concurrent Tasks DAG Capacity
mw1.micro 1 vCPU / 3GB 1 vCPU / 3GB 3 Up to 25

For mw1.micro, we maintain the general architecture of Amazon MWAA, and combine the Airflow scheduler and worker into a single container. For this reason, mw1.micro uses only two AWS Fargate tasks, one scheduler/worker hybrid, and one web server. The following diagram illustrates the environment architecture.

Another important change is that the meta database will now use a t4g.medium Amazon Aurora PostgreSQL-Compatible Edition instance powered by AWS Graviton2. With the Graviton2 family of processors, you get compute, storage, and networking improvements, and the reduction of your carbon footprint offered by the AWS family of processors.

Supported features

mw1.micro maintains Amazon MWAA and Airflow key functionalities that developers currently rely on:

  • You can set up a public or private web server, allowing you to control access to your Airflow UI as needed
  • You can add custom plugins and requirements, enabling you to extend Airflow’s capabilities and manage dependencies effortlessly
  • Startup scripts can be used to perform initialization tasks, making sure your environment is configured precisely to your specifications
  • The Airflow UI is fully functional, providing the same intuitive interface for managing and monitoring your workflows
  • It has the same networking features as other Amazon MWAA environment classes, such as custom URLs and shared virtual private cloud (VPC) support
  • Scheduler and worker logs remain separate in their respective Amazon CloudWatch log groups, providing ease of monitoring and troubleshooting

Considerations

The architectural decisions behind mw1.micro reflect a balance between functionality and cost-effectiveness. Here are the constraints the limited resources in mw1.micro brings:

  • The scheduler and worker are combined into a single Fargate task. Only a single scheduler/worker container is supported.
  • micro consists of a single Fargate task for the web server. The maximum number of web servers is 1.
  • The number of concurrent Airflow tasks in the worker (worker_autoscale) can be set to a maximum value of 3.

Pricing and availability

Amazon MWAA pricing dimensions remains unchanged, and you only pay for what you use:

  • The environment class
  • Metadata database storage consumed

Metadata database storage pricing remains the same. Refer to Amazon Managed Workflows for Apache Airflow Pricing for rates and more details.

Observe Amazon MWAA performance

When you start using the new environment class, it’s important to understand its behavior for maintaining optimal operation and identifying potential capacity issues. It’s essential to monitor key metrics such as metadata database memory usage, and CPU utilization of the worker/scheduler hybrid container. We recommend following the guidance described in Introducing container, database, and queue utilization metrics for Amazon MWAA to better understand the state of your environments, and get insights to right-size your resources.

Set up a new micro environment in Amazon MWAA

You can set up an Amazon MWAA micro environment in your account and preferred AWS Region using the AWS Management Console, API, or AWS Command Line Interface (AWS CLI). If you’re adopting infrastructure as code (IaC), you can automate the setup using AWS CloudFormation, the AWS Cloud Development Kit (AWS CDK), or Terraform scripts.

The Amazon MWAA micro environment class is available today in all Regions where Amazon MWAA is currently available.

Conclusion

In this post, we announced the availability of the new micro environment class in Amazon MWAA. This offering addresses the needs of teams working on smaller projects, proof-of-concept initiatives, or those requiring isolated environments for different departments. By providing a lightweight yet feature-rich solution, mw1.micro enables organizations to achieve substantial cost savings without compromising on essential functionalities.

As you explore the possibilities of mw1.micro, remember to monitor its performance using the recommended metrics to maintain optimal operation. With its availability across all Regions where Amazon MWAA is offered, your teams can now use the power of Airflow in a more streamlined and economical manner, opening up new opportunities for efficient data pipeline management and orchestration in the cloud.

For additional details and code examples on Amazon MWAA, visit the Amazon MWAA User Guide and the Amazon MWAA examples GitHub repo.

Apache, Apache Airflow, and Airflow are either registered trademarks or trademarks of the Apache Software Foundation in the United States and/or other countries.


About the Authors

Hernan Garcia is a Senior Solutions Architect at AWS based in the Netherlands. He works in the financial services industry, supporting enterprises in their cloud adoption. He is passionate about serverless technologies, security, and compliance. He enjoys spending time with family and friends, and trying out new dishes from different cuisines.

Sriharsh Adari is a Senior Solutions Architect at AWS, where he helps customers work backward from business outcomes to develop innovative solutions on AWS. Over the years, he has helped multiple customers on data platform transformations across industry verticals. His core area of expertise includes technology strategy, data analytics, and data science. In his spare time, he enjoys playing sports, watching TV shows, and playing Tabla.