Tag Archives: Featured

Introducing Amazon Nova: Frontier intelligence and industry leading price performance

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/introducing-amazon-nova-frontier-intelligence-and-industry-leading-price-performance/

Today, we’re thrilled to announce Amazon Nova, a new generation of state-of-the-art foundation models (FMs) that deliver frontier intelligence and industry leading price performance, available exclusively in Amazon Bedrock.

You can use Amazon Nova to lower costs and latency for almost any generative AI task. You can build on Amazon Nova to analyze complex documents and videos, understand charts and diagrams, generate engaging video content, and build sophisticated AI agents, from across a range of intelligence classes optimized for enterprise workloads.

Whether you’re developing document processing applications that need to process images and text, creating marketing content at scale, or building AI assistants that can understand and act on visual information, Amazon Nova provides the intelligence and flexibility you need with two categories of models: understanding and creative content generation.

Amazon Nova understanding models accept text, image, or video inputs to generate text output. Amazon creative content generation models accept text and image inputs to generate image or video output.

Understanding models: Text and visual intelligence
The Amazon Nova models include three understanding models (with a fourth one coming soon) designed to meet different needs:

Amazon Nova Micro – A text-only model that delivers the lowest latency responses in the Amazon Nova family of models at a very low cost. With a context length of 128K tokens and optimized for speed and cost, Amazon Nova Micro excels at tasks such as text summarization, translation, content classification, interactive chat and brainstorming, and simple mathematical reasoning and coding. Amazon Nova Micro also supports customization on proprietary data using fine-tuning and model distillation to boost accuracy.

Amazon Nova Lite – A very low-cost multimodal model that is lightning fast for processing image, video, and text inputs to generate text output. Amazon Nova Lite can handle real-time customer interactions, document analysis, and visual question-answering tasks with high accuracy. The model processes inputs up to 300K tokens in length and can analyze multiple images or up to 30 minutes of video in a single request. Amazon Nova Lite also supports text and multimodal fine-tuning and can be optimized to deliver the best quality and costs for your use case with techniques such as model distillation.

Amazon Nova Pro – A highly capable multimodal model with the best combination of accuracy, speed, and cost for a wide range of tasks. Amazon Nova Pro is capable of processing up to 300K input tokens and sets new standards in multimodal intelligence and agentic workflows that require calling APIs and tools to complete complex workflows. It achieves state-of-the-art performance on key benchmarks including visual question answering (TextVQA) and video understanding (VATEX). Amazon Nova Pro demonstrates strong capabilities in processing both visual and textual information and excels at analyzing financial documents. With an input context of 300K tokens, it can process code bases with over fifteen thousand lines of code. Amazon Nova Pro also serves as a teacher model to distill custom variants of Amazon Nova Micro and Lite.

Amazon Nova Premier – Our most capable multimodal model for complex reasoning tasks and for use as the best teacher for distilling custom models. Amazon Nova Premier is still in training. We’re targeting availability in early 2025.

Amazon Nova understanding models excel in Retrieval-Augmented Generation (RAG), function calling, and agentic applications. This is reflected in Amazon Nova model scores in the Comprehensive RAG Benchmark (CRAG) evaluation, Berkeley Function Calling Leaderboard (BFCL), VisualWebBench, and Mind2Web.

What makes Amazon Nova particularly powerful for enterprises is its customization capabilities. Think of it as tailoring a suit: you start with a high-quality foundation and adjust it to fit your exact needs. You can fine-tune the models with text, image, and video to understand your industry’s terminology, align with your brand voice, and optimize for your specific use cases. For instance, a legal firm might customize Amazon Nova to better understand legal terminology and document structures.

You can see the latest benchmark scores for these models on the Amazon Nova product page.

Creative content generation: Bringing concepts to life
The Amazon Nova models also include two creative content generation models:

Amazon Nova Canvas – A state-of-the-art image generation model producing studio-quality images with precise control over style and content, including rich editing features such as inpainting, outpainting, and background removal. Amazon Nova Canvas excels on human evaluations and key benchmarks such as text-to-image faithfulness evaluation with question answering (TIFA) and ImageReward.

Amazon Nova Reel – A state-of-the-art video generation model. Using Amazon Nova Reel, you can produce short videos through text prompts and images, control visual style and pacing, and generate professional-quality video content for marketing, advertising, and entertainment. Amazon Nova Reel outperforms existing models on human evaluations of video quality and video consistency.

All Amazon Nova models include built-in safety controls and creative content generation models include watermarking capabilities to promote responsible AI use.

Let’s see how these models work in practice for a few use cases.

Using Amazon Nova Pro for document analysis
To demonstrate the capabilities of document analysis, I downloaded the Choosing a generative AI service decision guide in PDF format from the AWS documentation.

First, I choose Model access in the Amazon Bedrock console navigation pane and request access to the new Amazon Nova models. Then, I choose Chat/text in the Playground section of the navigation pane and select the Amazon Nova Pro model. In the chat, I upload the decision guide PDF and ask:

Write a summary of this doc in 100 words. Then, build a decision tree.

The output follows my instructions producing a structured decision tree that gives me a glimpse of the document before reading it.

Console screenshot.

Using Amazon Nova Pro for video analysis
To demonstrate video analysis, I prepared a video by joining two short clips (more on this in the next section):

This time, I use the AWS SDK for Python (Boto3) to invoke the Amazon Nova Pro model using the Amazon Bedrock Converse API and analyze the video:

import boto3

AWS_REGION = "us-east-1"
MODEL_ID = "amazon.nova-pro-v1:0"
VIDEO_FILE = "the-sea.mp4"

bedrock_runtime = boto3.client("bedrock-runtime", region_name=AWS_REGION)
with open(VIDEO_FILE, "rb") as f:
    video = f.read()

user_message = "Describe this video."

messages = [ { "role": "user", "content": [
    {"video": {"format": "mp4", "source": {"bytes": video}}},
    {"text": user_message}
] } ]

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=messages,
    inferenceConfig={"temperature": 0.0}
 )

response_text = response["output"]["message"]["content"][0]["text"]
print(response_text)

Amazon Nova Pro can analyze videos that are uploaded with the API (as in the previous code) or that are stored in an Amazon Simple Storage Service (Amazon S3) bucket.

In the script, I ask to describe the video. I run the script from the command line. Here’s the result:

The video begins with a view of a rocky shore on the ocean, and then transitions to a close-up of a large seashell resting on a sandy beach.

I can use a more detailed prompt to extract specific information from the video such as objects or text. Note that Amazon Nova currently does not process audio in a video.

Using Amazon Nova for video creation
Now, let’s create a video using Amazon Nova Reel, starting from a text-only prompt and then providing a reference image.

Because generating a video takes a few minutes, the Amazon Bedrock API introduced three new operations:

StartAsyncInvoke – To start an asynchronous invocation

GetAsyncInvoke – To get the current status of a specific asynchronous invocation

ListAsyncInvokes – To list the status of all asynchronous invocations with optional filters such as status or date

Amazon Nova Reel supports camera control actions such as zooming or moving the camera. This Python script creates a video from this text prompt:

Closeup of a large seashell in the sand. Gentle waves flow all around the shell. Sunset light. Camera zoom in very close.

After the first invocation, the script periodically checks the status until the creation of the video has been completed. I pass a random seed to get a different result each time the code runs.

import random
import time

import boto3

AWS_REGION = "us-east-1"
MODEL_ID = "amazon.nova-reel-v1:0"
SLEEP_TIME = 30
S3_DESTINATION_BUCKET = "<BUCKET>"

video_prompt = "Closeup of a large seashell in the sand. Gentle waves flow all around the shell. Sunset light. Camera zoom in very close."

bedrock_runtime = boto3.client("bedrock-runtime", region_name=AWS_REGION)
model_input = {
    "taskType": "TEXT_VIDEO",
    "textToVideoParams": {"text": video_prompt},
    "videoGenerationConfig": {
        "durationSeconds": 6,
        "fps": 24,
        "dimension": "1280x720",
        "seed": random.randint(0, 2147483648)
    }
}

invocation = bedrock_runtime.start_async_invoke(
    modelId=MODEL_ID,
    modelInput=model_input,
    outputDataConfig={"s3OutputDataConfig": {"s3Uri": f"s3://{S3_DESTINATION_BUCKET}"}}
)

invocation_arn = invocation["invocationArn"]
s3_prefix = invocation_arn.split('/')[-1]
s3_location = f"s3://{S3_DESTINATION_BUCKET}/{s3_prefix}"
print(f"\nS3 URI: {s3_location}")

while True:
    response = bedrock_runtime.get_async_invoke(
        invocationArn=invocation_arn
    )
    status = response["status"]
    print(f"Status: {status}")
    if status != "InProgress":
        break
    time.sleep(SLEEP_TIME)

if status == "Completed":
    print(f"\nVideo is ready at {s3_location}/output.mp4")
else:
    print(f"\nVideo generation status: {status}")

I run the script:

Status: InProgress
. . .
Status: Completed

Video is ready at s3://BUCKET/PREFIX/output.mp4

After a few minutes, the script completes and prints the output Amazon Simple Storage Service (Amazon S3) location. I download the output video using the AWS Command Line Interface (AWS CLI):

aws s3 cp s3://BUCKET/PREFIX/output.mp4 ./output-from-text.mp4

This is the resulting video. As requested, the camera zooms in on the subject.

Using Amazon Nova Reel with a reference image
To have better control over the creation of the video, I can provide Amazon Nova Reel a reference image such as the following:

A seascape image.

This script uses the reference image and a text prompt with a camera action (drone view flying over a coastal landscape) to create a video:

import base64
import random
import time

import boto3

S3_DESTINATION_BUCKET = "<BUCKET>"
AWS_REGION = "us-east-1"
MODEL_ID = "amazon.nova-reel-v1:0"
SLEEP_TIME = 30
input_image_path = "seascape.png"
video_prompt = "drone view flying over a coastal landscape"

bedrock_runtime = boto3.client("bedrock-runtime", region_name=AWS_REGION)

# Load the input image as a Base64 string.
with open(input_image_path, "rb") as f:
    input_image_bytes = f.read()
    input_image_base64 = base64.b64encode(input_image_bytes).decode("utf-8")

model_input = {
    "taskType": "TEXT_VIDEO",
    "textToVideoParams": {
        "text": video_prompt,
        "images": [{ "format": "png", "source": { "bytes": input_image_base64 } }]
        },
    "videoGenerationConfig": {
        "durationSeconds": 6,
        "fps": 24,
        "dimension": "1280x720",
        "seed": random.randint(0, 2147483648)
    }
}

invocation = bedrock_runtime.start_async_invoke(
    modelId=MODEL_ID,
    modelInput=model_input,
    outputDataConfig={"s3OutputDataConfig": {"s3Uri": f"s3://{S3_DESTINATION_BUCKET}"}}
)

invocation_arn = invocation["invocationArn"]
s3_prefix = invocation_arn.split('/')[-1]
s3_location = f"s3://{S3_DESTINATION_BUCKET}/{s3_prefix}"

print(f"\nS3 URI: {s3_location}")

while True:
    response = bedrock_runtime.get_async_invoke(
        invocationArn=invocation_arn
    )
    status = response["status"]
    print(f"Status: {status}")
    if status != "InProgress":
        break
    time.sleep(SLEEP_TIME)
if status == "Completed":
    print(f"\nVideo is ready at {s3_location}/output.mp4")
else:
    print(f"\nVideo generation status: {status}")

Again, I download the output using the AWS CLI:

aws s3 cp s3://BUCKET/PREFIX/output.mp4 ./output-from-image.mp4

This is the resulting video. The camera starts from the reference image and moves forward.

Building AI responsibly
Amazon Nova models are built with a focus on customer safety, security, and trust throughout the model development stages, offering you peace of mind as well as an adequate level of control to enable your unique use cases.

We’ve built in comprehensive safety features and content moderation capabilities, giving you the controls you need to use AI responsibly. Every generated image and video include digital watermarking.

The Amazon Nova foundation models are built with protections that match its increased capabilities. Amazon Nova extends our safety measures to combat the spread of misinformation, child sexual abuse material (CSAM), and chemical, biological, radiological, or nuclear (CBRN) risks.

Things to know
Amazon Nova models are available in Amazon Bedrock in the US East (N. Virginia) AWS region. Amazon Nova Micro, Lite, and Pro are also available in the US West (Oregon), and US East (Ohio) regions via cross-Region inference. As usual with Amazon Bedrock, the pricing follows a pay-as-you-go model. For more information, see Amazon Bedrock pricing.

The new generation of Amazon Nova understanding models speaks your language. These models understand and generate content in over 200 languages, with particularly strong capabilities in English, German, Spanish, French, Italian, Japanese, Korean, Arabic, Simplified Chinese, Russian, Hindi, Portuguese, Dutch, Turkish, and Hebrew. This means you can build truly global applications without worrying about language barriers or maintaining separate models for different regions. Amazon Nova models for creative content generation support English prompts.

As you explore Amazon Nova, you’ll discover its ability to handle increasingly complex tasks. You can use these models to process lengthy documents up to 300K tokens, analyze multiple images in a single request, understand up to 30 minutes of video content, and generate images and videos at scale from natural language. This makes these models suitable for a variety of business use cases, from quick customer service interactions to deep analysis of corporate documentation and asset creation for advertising, ecommerce, and social media applications.

Integration with Amazon Bedrock makes deployment and scaling straightforward. You can leverage features like Amazon Bedrock Knowledge Bases to enhance your model with proprietary information, use Amazon Bedrock Agents to automate complex workflows, and implement Amazon Bedrock Guardrails to promote responsible AI use. The platform supports real-time streaming for interactive applications, batch processing for high-volume workloads, and detailed monitoring to help you optimize performance.

Ready to start building with Amazon Nova? Give the new models a try in the Amazon Bedrock console today, visit the Amazon Nova models section of the Amazon Bedrock documentation, and send feedback to AWS re:Post for Amazon Bedrock. You can find deep-dive technical content and discover how our Builder communities are using Amazon Bedrock at community.aws. Let us know what you build with these new models!

Danilo

Troubleshooting Disaster Recovery Scenarios: 10 Mistakes to Avoid

Post Syndicated from Kari Rivas original https://www.backblaze.com/blog/troubleshooting-disaster-recovery-scenarios-10-mistakes-to-avoid/

A decorative image showing a hammer smashing a drive.

When it comes to disaster recovery (DR), hope isn’t a plan. Yet I’ve seen the same story play out too many times: Companies find themselves scrambling when the unthinkable happens, discovering that their disaster recovery strategy is, well, full of holes. It’s like packing a parachute: You don’t want to find out what you missed when you’re already falling through the air. From my experience, there are some common mistakes businesses make that can turn a manageable problem into a fire drill. 

In this post, I’m sharing the top 10 disaster recovery mistakes I’ve come across when helping businesses think through their disaster recovery posture so that you can strengthen your own safety net. By avoiding these mistakes and implementing a comprehensive DR plan, you can ensure a rapid and efficient recovery from unforeseen disruptions.

1. Proximity paradox

A geographically close disaster recovery site offers limited protection. A natural disaster impacting your primary location could easily disable the nearby DR facility as well. And, if you don’t have a DR site, this could still apply to your business if you keep your backups nearby, such as in a tape storage facility down the road.

How Pittsburg State solved the proximity paradox

Pittsburg State University is located in Kansas in the heart of tornado alley. Disaster planning is nonnegotiable, and the university didn’t want to take chances with their data. See how they set up a robust private cloud with nodes across the state and backed all of their data up to immutable cloud storage with Backblaze B2.

Read the Story ➔ 

2. Untested backups

Backups that haven’t been restored and verified are unreliable. Regularly test your backups to ensure a smooth recovery process during a disaster.

3. Replication trap

Relying solely on replication for DR creates a single point of failure. If your primary site is compromised, the replicated data at the DR site might be compromised as well. Off-site full and incremental backups are essential.

4. Paper plan peril

A DR plan gathering dust on a shelf is useless. Conduct regular drills to simulate disaster scenarios and expose weaknesses in your plan.

5. Snapshot snafu

Snapshots are not comprehensive backups. Using snapshots for long term storage and retention introduces both technical and compliance risks in relation to how snapshots are managed. This affects both cloud and on-premises platforms.

6. SaaS surprises

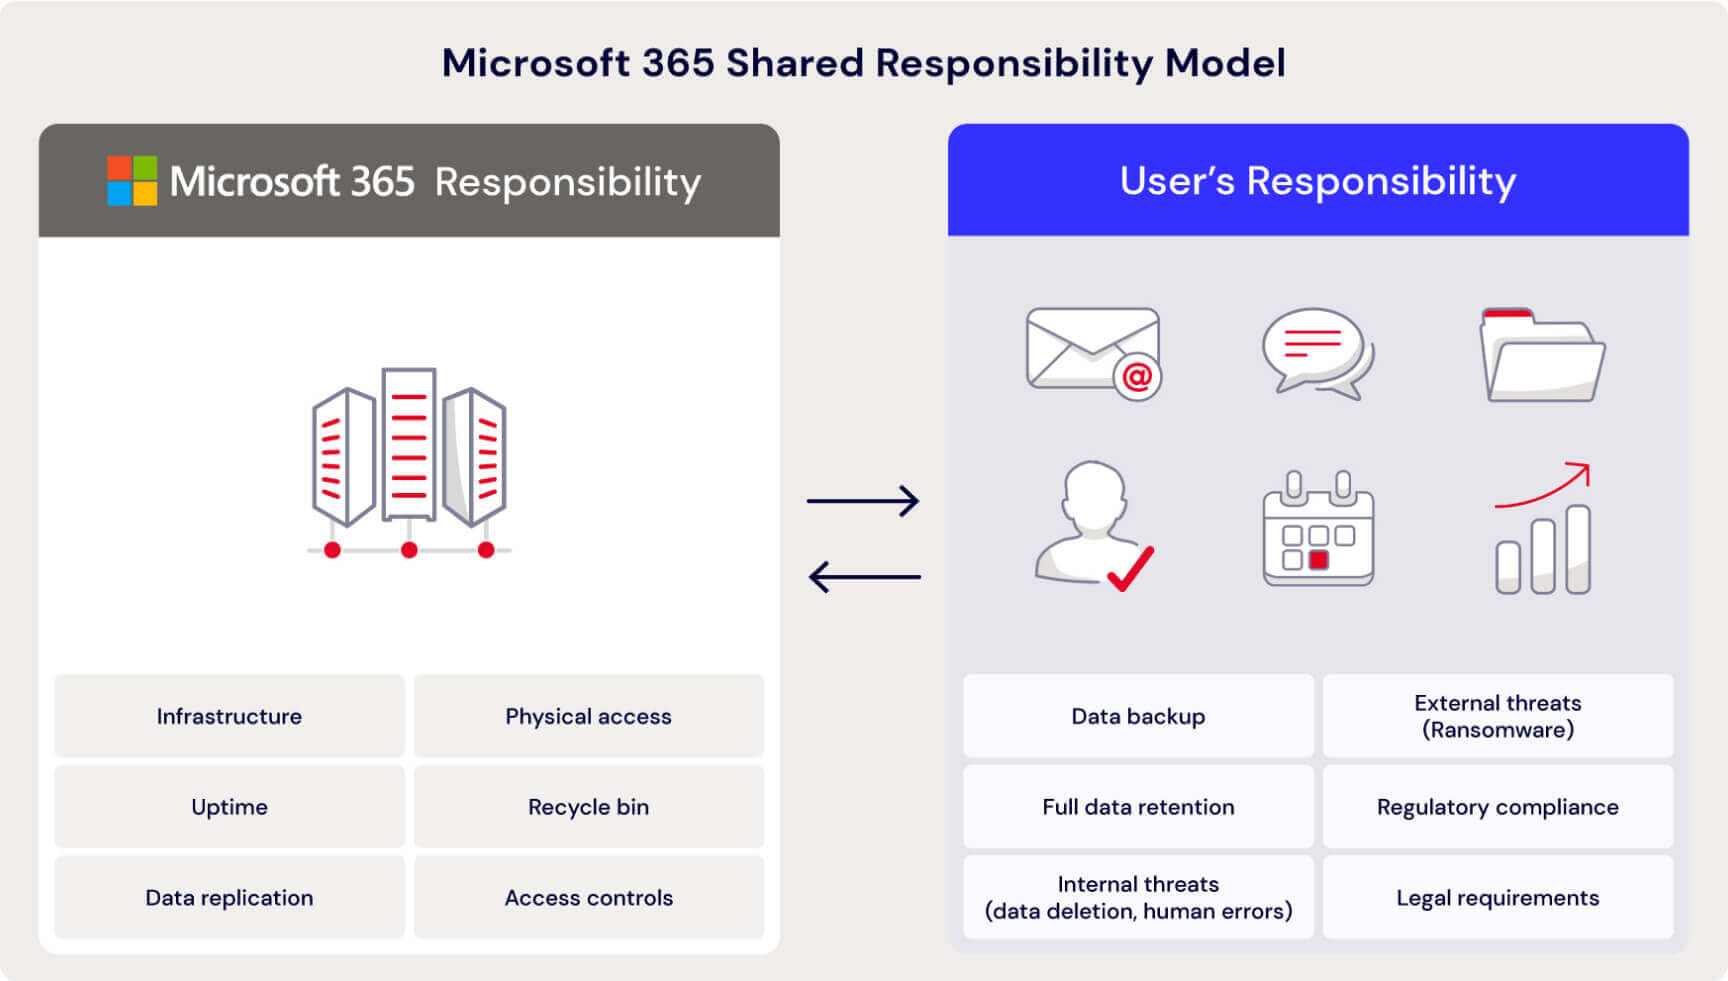
Software as a service (SaaS) providers like Microsoft 365 and Google Workspace focus on high availability, but they operate on a shared responsibility model, meaning they may have limited built-in protection and recovery options. You may not be managing servers, but you do need a comprehensive data protection plan including regular, incremental backups outside of the SaaS platform.

7. Unforeseen force majeure

Disasters come in all shapes and sizes. Don’t limit your DR plan to common IT disruptions. Consider scenarios like widespread power outages or communication breakdowns, and plan accordingly. The goal is holistic cyber resilience—not only identifying threats and protecting against them, but also withstanding attacks as they’re happening and responding effectively.

8. Backup infiltration

Bad actors are increasingly targeting backups to increase the chances of a payout. Utilize immutable backups, unchangeable after creation, for an extra layer of protection against ransomware attacks.

9. Cloud drive disasters

Storing data on Google Drive, Dropbox, OneDrive, etc. is incredibly common. But these platforms do not protect against ransomware and provide limited point-in-time recovery options. Cloud drives are not a sufficient backup of your data.

10. Overlooking compliance

Factor in compliance needs when building your data protection and DR strategy. Regulations like HIPAA, GDPR, and others may have security or archival requirements that should be considered in your plan.

Invest in cyber resilience

After working in the disaster recovery space, I can tell you this: It’s not just about having a plan; it’s about having one that works when it counts. The mistakes I’ve covered here are common, but they’re also avoidable. Take the time to address these now, and you’re not only protecting your systems and data, but your company’s future. For me, a strong DR plan is an investment in resilience, and it’s there to catch you when you need it most.

The post Troubleshooting Disaster Recovery Scenarios: 10 Mistakes to Avoid appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Introducing multi-agent collaboration capability for Amazon Bedrock (preview)

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/introducing-multi-agent-collaboration-capability-for-amazon-bedrock/

Today, we’re announcing the multi-agent collaboration capability for Amazon Bedrock (preview). With multi-agent collaboration, you can build, deploy, and manage multiple AI agents working together on complex multi-step tasks that require specialized skills.

When you need more than a single agent to handle a complex task, you can create additional specialized agents to address different aspects of the process. However, managing these agents becomes technically challenging as tasks grow in complexity. As a developer using open source solutions, you may find yourself navigating the complexities of agent orchestration, session handling, memory management, and other technical aspects that require manual implementation.

With the fully managed multi-agent collaboration capability on Amazon Bedrock, specialized agents work within their domains of expertise, coordinated by a supervisor agent. The supervisor breaks down requests, delegates tasks, and consolidates outputs into a final response. For example, an investment advisory multi-agent system might include agents specialized in financial data analysis, research, forecasting, and investment recommendations. Similarly, a retail operations multi-agent system could handle demand forecasting, inventory allocation, supply chain coordination, and pricing optimization.

Amazon Bedrock Agents manages the collaboration, communication, and task delegation behind the scenes. By enabling agents to work together, you can achieve higher task success rates, accuracy, and enhanced productivity. In internal benchmark testing, multi-agent collaboration has shown marked improvements compared to single-agent systems for handling complex, multi-step tasks.

Highlights of multi-agent collaboration in Amazon Bedrock
A key challenge in building effective multi-agent collaboration systems is managing the complexity and overhead of coordinating multiple specialized agents at scale. Amazon Bedrock simplifies the process of building, deploying, and orchestrating effective multi-agent collaboration systems while addressing efficiency challenges through several key features and optimizations:

  • Quick setup – Create, deploy, and manage AI agents working together in minutes without the need for complex coding.
  • Composability – Integrate your existing agents as subagents within a larger agent system, allowing them to seamlessly work together to tackle complex workflows.
  • Efficient inter-agent communication – The supervisor agent can interact with subagents using a consistent interface, supporting parallel communication for more efficient task completion.
  • Optimized collaboration modes – Choose between supervisor mode and supervisor with routing mode. With routing mode, the supervisor agent will route simple requests directly to specialized subagents, bypassing full orchestration. For complex queries or when no clear intention is detected, it automatically falls back to the full supervisor mode, where the supervisor agent analyzes, breaks down problems, and coordinates multiple subagents as needed.
  • Integrated trace and debug console – Visualize and analyze multi-agent interactions behind the scenes using the integrated trace and debug console.

These features collectively improve coordination capabilities, communication speed, and overall effectiveness of the multi-agent collaboration framework in tackling complex, real-world problems.

Here’s how to get started.

Using multi-agent collaboration in Amazon Bedrock
For this demo, I create a social media campaign manager agent that’s composed of a content strategist agent creating posts and an engagement predictor agent optimizing their timing and reach. The following figure shows the team of agents that I’m creating and how multi-agent collaboration works in this scenario.

Multi-agent collaboration in Amazon Bedrock

To get started, you can use the Amazon Bedrock console or APIs to create a supervisor agent and associate specialist subagents in just a few steps.

Create subagents
First, I create the two subagents using the existing agent builder workflow. I open the Amazon Bedrock console, select Agents in the left navigation panel, then choose Create Agent. I create one agent that I name content-strategist, an agent that generates creative social media content ideas. Note the new option to enable the agent for multi-agent collaboration. I leave this option unchecked for now; we need to enable this option later for the supervisor agent. Next, I choose Create.

Multi-agent collaboration in Amazon Bedrock

In the Agent builder dialog box, I choose to create and use a new service role, select Anthropic’s Claude 3.5 Sonnet v2 as the model, and provide the following instructions for the agent:

You are a social media content strategist with expertise in converting business goals into engaging social posts. Your task is to generate creative, on-brand content ideas that align with specified campaign goals and target audience. Each suggestion should include a topic, content type (image/video/text/poll), specific copy, and relevant hashtags. Focus on variety, authenticity, and ensuring each post serves a strategic purpose.

I also create and attach a knowledge base that contains high-performing post templates. As with any other agent, you could also configure additional settings, such as action groups to perform tasks, enable code interpretation, or add guardrails. I leave all other settings to their defaults.

Multi-agent collaboration in Amazon Bedrock

Then, I choose Save and exit.

I repeat the steps to create a second agent that I name engagement-predictor, an agent that predicts social media post performance and optimal posting times. For this agent, I provide the following instructions:

You are a social media analytics expert who predicts post performance and optimal timing. For each content idea, analyze potential reach and engagement based on content type, industry benchmarks, and audience behavior patterns. Your task is to estimate reach, engagement rate, and determine the best posting time (day/hour). Support each prediction with data-driven reasoning and industry-specific insights. Focus on actionable metrics that will maximize campaign impact.

I create and attach a knowledge base that contains platform-specific peak engagement times, industry benchmark metrics, and content performance multipliers for predicting and optimizing social media post performance. Again, I choose Save and exit.

I now have my two specialist subagents.

Multi-agent collaboration in Amazon Bedrock

Before moving on, test each agent individually, and once you’ve confirmed their functionality, create an alias for each one. This approach will streamline the process of creating supervisor agents in the future.

Create supervisor agent and associate subagents
Next, I create the supervisor agent. I name this agent social-media-campaign-manager, an agent that combines the outputs from the content strategy agent and the engagement predictor agent into a comprehensive campaign plan.

This time, I turn on Enable Multi-agent collaboration before I choose Create.

Enable multi-agent collaboration in Amazon Bedrock

In the Agent builder dialog box, I again choose to create and use a new service role, select Anthropic’s Claude 3.5 Sonnet v2 as the model, and provide the following instructions for the agent:

You are a strategic campaign manager who orchestrates social media campaigns from concept to execution.

Multi-agent collaboration in Amazon Bedrock

I create and attach a knowledge base that contains a collection of proven campaign templates, content mix ratios, and cross-platform posting requirements.

Next, I scroll down to Multi-agent collaboration and choose Edit.

Multi-agent collaboration in Amazon Bedrock

The option to turn on multi-agent collaboration should already be checked because I enabled this option when I started creating the agent.

Multi-agent collaboration in Amazon Bedrock

Then, you can choose between two collaboration configurations that determine how information is handled across the agent’s team to coordinate a final response.

In Supervisor mode, the supervisor agent analyzes the input, breaking down complex problems or paraphrasing the request. It then invokes subagents either serially or in parallel, and it might consult knowledge bases or invoke action groups. After receiving responses from subagents, the supervisor agent processes them to determine if the problem is solved or if further action is needed.

Alternatively, in Supervisor with routing mode, the supervisor agent first attempts to route simple requests directly to a relevant subagent, whose response is then forwarded to the user. For complex or ambiguous inputs, the system switches to supervisor mode, where the supervisor agent breaks down the problem or asks follow-up questions before proceeding similarly to standard supervisor mode. This approach allows for efficient handling of both straightforward and complex queries within a single framework.

For my demo, I choose Supervisor mode.

As a last step, I associate the two subagents by adding each subagent in Agent collaborator. I provide a collaborator name for each agent and a collaborator instruction.

I select the content-strategist agent and provide the collaborator name content-strategist along with the following instruction:

You can invoke this agent for social media content strategy tasks such as converting business goals into engaging social posts. The agent generates creative, on-brand content ideas that align with specified campaign goals and target audience.

Multi-agent collaboration in Amazon Bedrock

Then, I choose Add collaborator, select the engagement-predictor agent, and provide the collaborator name engagement-predictor along with the following instructions:

You can invoke this agent for social media analytics to predict post performance and optimal timing.

Multi-agent collaboration in Amazon Bedrock

Note: Enable conversation history sharing allows the supervisor agent to pass the full context of a user interaction to subagents. This helps maintain coherence and avoid repeating questions, especially when routing or switching between agents. Keep in mind, it might confuse simpler subagents with complex task histories. We recommend enabling this feature when you need continuity and disabling it when you’re focusing on task simplification or using specialized agents. I keep it disabled for my demo.

Choose Save and complete the Agent builder workflow.

Let’s test it!

Test multi-agent collaboration
Prepare the social media campaign manager agent and choose Test.

I use the following input prompt:

Create a 2-week social campaign for EcoTech's new solar panel launch. Target: B2B (facility managers, sustainability directors) Key points: 30% more efficient, AI-optimized, 2-year ROI Need: 4 posts/week on LinkedIn/Twitter (40% educational, 30% product, 30% thought leadership).

After the response comes back, I choose Show trace to inspect the workflow. In the Multi-agent collaboration trace timeline, you can observe that each subagent got invoked. You can also inspect the trace steps to check the orchestration details.

Multi-agent collaboration in Amazon Bedrock

You can find more examples of how to work with Amazon Bedrock Agents and the new multi-agent collaboration capability in the Amazon Bedrock Agent Samples GitHub repo.

Things to know

  • During preview, multi-agent collaboration supports real-time chat assistant (synchronous) use cases.
  • Subagents can have collaboration enabled themselves with an overall soft limit of three hierarchical agent team layers.

Join the preview
Multi-agent collaboration in Amazon Bedrock is available today in preview in all AWS Regions that support Amazon Bedrock Agents, except AWS GovCloud (US-West). Check the full Region list for future updates. To learn more, visit Amazon Bedrock Agents.

Give multi-agent collaboration a try in the Amazon Bedrock console today and let us know what you think! Send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

I’m excited to see what you build with multi-agent collaboration.

— Antje

Prevent factual errors from LLM hallucinations with mathematically sound Automated Reasoning checks (preview)

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/prevent-factual-errors-from-llm-hallucinations-with-mathematically-sound-automated-reasoning-checks-preview/

Today, we’re adding Automated Reasoning checks (preview) as a new safeguard in Amazon Bedrock Guardrails to help you mathematically validate the accuracy of responses generated by large language models (LLMs) and prevent factual errors from hallucinations.

Amazon Bedrock Guardrails lets you implement safeguards for generative AI applications by filtering undesirable content, redacting personal identifiable information (PII), and enhancing content safety and privacy. You can configure policies for denied topics, content filters, word filters, PII redaction, contextual grounding checks, and now Automated Reasoning checks.

Automated Reasoning checks help prevent factual errors from hallucinations using sound mathematical, logic-based algorithmic verification and reasoning processes to verify the information generated by a model, so outputs align with known facts and aren’t based on fabricated or inconsistent data.

Amazon Bedrock Guardrails is the only responsible AI capability offered by a major cloud provider that helps customers to build and customize safety, privacy, and truthfulness for their generative AI applications within a single solution.

Automated Reasoning checks in Amazon Bedrock Guardrails

Primer on automated reasoning
Automated reasoning is a field of computer science that uses mathematical proofs and logical deduction to verify the behavior of systems and programs. Automated reasoning differs from machine learning (ML), which makes predictions, in that it provides mathematical guarantees about a system’s behavior. Amazon Web Services (AWS) already uses automated reasoning in key service areas such as storage, networking, virtualization, identity, and cryptography. For example, automated reasoning is used to formally verify the correctness of cryptographic implementations, improving both performance and development speed. To learn more, check out Provable Security and the Automated reasoning research area in the Amazon Science Blog.

Now AWS is applying a similar approach to generative AI. The new Automated Reasoning checks (preview) in Amazon Bedrock Guardrails is the first and only generative AI safeguard that helps prevent factual errors due to hallucinations using logically accurate and verifiable reasoning that explains why generative AI responses are correct. Automated Reasoning checks are particularly useful for use cases where factual accuracy and explainability are important. For example, you could use Automated Reasoning checks to validate LLM-generated responses about human resources (HR) policies, company product information, or operational workflows.

Used alongside other techniques such as prompt engineering, Retrieval-Augmented Generation (RAG), and contextual grounding checks, Automated Reasoning checks add a more rigorous and verifiable approach to making sure that LLM-generated output is factually accurate. By encoding your domain knowledge into structured policies, you can have confidence that your conversational AI applications are providing reliable and trustworthy information to your users.

Using Automated Reasoning checks (preview) in Amazon Bedrock Guardrails
With Automated Reasoning checks in Amazon Bedrock Guardrails, you can create Automated Reasoning policies that encode your organization’s rules, procedures, and guidelines into a structured, mathematical format. These policies can then be used to verify that the content generated by your LLM-powered applications is consistent with your guidelines.

Automated Reasoning policies are composed of a set of variables, defined with a name, type, and description, and the logical rules that operate on the variables. Behind the scenes, rules are expressed in formal logic, but they’re translated to natural language to make it easier for a user without formal logic expertise to refine a model. Automated Reasoning checks uses the variable descriptions to extract their values when validating a Q&A.

Here’s how it works.

Create Automated Reasoning policies
Using the Amazon Bedrock console, you can upload documents that describe your organization’s rules and procedures. Amazon Bedrock will analyze these documents and automatically create an initial Automated Reasoning policy, which represents the key concepts and their relationships in a mathematical format.

Navigate to the new Automated Reasoning menu item in Safeguards. Create a new policy and give it a name. Upload an existing document that defines the right solution space, such as an HR guideline or an operational manual. For this demo, I’m using an example airline ticket policy document that includes the airline’s policies for ticket changes.

Then, define the policy’s intent and any processing parameters. For example, specify if it will validate airport staff inquiries and identify any elements to exclude from processing, such as internal reference numbers. Include one or more sample Q&As to help the system understand typical interactions.

Automated Reasoning checks in Amazon Bedrock Guardrails

Here’s my intent description:

Ignore the policy ID number, it's irrelevant. Airline employees will ask questions about whether customers are allowed to modify their tickets providing the customer details. Below is an example question:

QUESTION: I’m flying to Wonder City with Unicorn Airlines and noticed my last name is misspelled on the ticket, can modify it at the airport?
ANSWER: No. Changes to the spelling of the names on the ticket must be submitted via email within 24 hours of ticket purchase.

Then, choose Create.

The system now initiates an automated process to create your Automated Reasoning policy. This process involves analyzing your document, identifying key concepts, breaking down the document into individual units, translating these natural language units into formal logic, validating the translations, and finally combining them into a comprehensive logical model. Once complete, review the generated structure, including the rules and variables. You can edit these for accuracy through the user interface.

Automated Reasoning checks in Amazon Bedrock Guardrails

To test the Automated Reasoning policy, you first have to create a guardrail.

Create a guardrail and configure Automated Reasoning checks
When building your conversational AI application with Amazon Bedrock Guardrails, you can enable Automated Reasoning checks and specify which Automated Reasoning policies to use for validation.

Navigate to the Guardrails menu item in Safeguards. Create a new guardrail and give it a name. Choose Enable Automated Reasoning policy and select the policy and policy version you want to use. Then, complete your guardrail configuration.

Automated Reasoning checks in Amazon Bedrock Guardrails

Test Automated Reasoning checks
You can use the Test playground in the Automated Reasoning console to verify the effectiveness of your Automated Reasoning policy. Enter a test question just like a user of your application would, together with an example answer to validate.

For this demo, I enter an incorrect answer to see what will happen.

Question: I'm flying to Wonder City with Unicorn Airlines and noticed my last name is misspelled on the ticket, I'm currently in person at the airport, can I submit the change in person?

Answer: Yes. You are allowed to change names on tickets at any time, even in person at the airport.

Then, select the guardrail you’ve just created and choose Submit.

Automated Reasoning checks in Amazon Bedrock Guardrails

Automated Reasoning checks will analyze the content and validate it against the Automated Reasoning policies you’ve configured. The checks will identify any factual inaccuracies or inconsistencies and provide an explanation for the validation results.

In my demo, the Automated Reasoning checks correctly identified the response as Invalid. It shows which rule led to the finding, along with the extracted variables and suggestions.

Automated Reasoning checks in Amazon Bedrock Guardrails

When the validation result is invalid, the suggestions show a set of variable assignments that would make the conclusion valid. In my scenario, the suggestions show that the change submission method needs to be email for the validation result to be valid.

If no factual inaccuracies are detected and the validation result is Valid, suggestions show a list of assignments that are necessary for the result to hold; these are unstated assumptions in the answer. In my scenario, this might be assumptions such as that it’s the original ticket on which name corrections must be made or that the type of ticket stock is eligible for changes.

If factual inconsistencies are detected, the console will display Mixed results as the validation result. In the API response, you will see a list of findings, with some marked as valid and others as invalid. If this happens, review the system’s findings and suggestions and edit any unclear policy rules.

You can also use the validation results to enhance LLM-generated responses based on the feedback. For example, the following code snippet demonstrates how you can ask the model to regenerate its answer based on the received feedback:

for f in findings:
    if f.result == "INVALID":
        if f.rules is not None:
            for r in f.rules:
                feedback += f"<feedback>{r.description}</feedback>\n"

new_prompt = (
    "The answer you generated is inaccurate. Consider the feedback below within "
    f"<feedback> tags and rewrite your answer.\n\n{feedback}"
)

Achieving high validation accuracy is an iterative process. As a best practice, regularly review policy performance and adjust it as needed. You can edit rules in natural language and the system will automatically update the logical model.

For example, updating variable descriptions can significantly improve validation accuracy. Consider a scenario where a question states, “I’m a full-time employee…,” and the description of the is_full_time variable only states, “works more than 20 hours per week.” In this case, Automated Reasoning checks might not recognize the phrase “full-time.” To enhance accuracy, you should update the variable description to be more comprehensive, such as: “Works more than 20 hours per week. Users may refer to this as full-time or part-time. The value should be true for full-time and false for part-time.” This detailed description helps the system pick up all relevant factual claims for validation in natural language questions and answers, providing more accurate results.

Available in preview
The new Automated Reasoning checks safeguard is available today in preview in Amazon Bedrock Guardrails in the US West (Oregon) AWS Region. To request to be considered for access to the preview today, contact your AWS account team. In the next few weeks, look for a sign-up form in the Amazon Bedrock console. To learn more, visit Amazon Bedrock Guardrails.

— Antje

Build faster, more cost-efficient, highly accurate models with Amazon Bedrock Model Distillation (preview)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/build-faster-more-cost-efficient-highly-accurate-models-with-amazon-bedrock-model-distillation-preview/

Today, we’re announcing the availability of Amazon Bedrock Model Distillation in preview that automates the process of creating a distilled model for your specific use case by generating responses from a large foundation model (FM) called a teacher model and fine-tunes a smaller FM called a student model with the generated responses. It uses data synthesis techniques to improve response from a teacher model. Amazon Bedrock then hosts the final distilled model for inference giving you a faster and more cost-efficient model with accuracy close to the teacher model, for your use case.

Customers are excited to use the most powerful and accurate FMs on Amazon Bedrock for their generative AI applications. But for some use cases, the latency associated with these models isn’t ideal. In addition, customers are looking for better price performance as they scale their generative AI applications to many billions of user interactions. To reduce latency and be more cost-efficient for their use case, customers are turning to smaller models. However, for some use cases, smaller models can’t provide optimal accuracy. Fine-tuning models requires an additional skillset to create the high-quality labeled datasets to increase model accuracy for customer’s use cases.

With Amazon Bedrock Model Distillation, you can increase the accuracy of a smaller-sized student model to mimic a higher-performance teacher model with the process of knowledge transfer. You can create distilled models that for a certain use case, are up to five times faster and up to 75 percent less expensive than original large models, with less than two percent accuracy loss for use cases such as Retrieval Augmented Generation (RAG), by transferring knowledge from a teacher model of your choice to a student model in the same family.

How does it work?
Amazon Bedrock Model Distillation generates responses from teacher models, improves response generation from a teacher model by adding proprietary data synthesis, and fine-tunes a student model.

Amazon Bedrock employs various data synthesis techniques to enhance response generation from the teacher model and create high-quality fine-tuning datasets. These techniques are tailored to specific use cases. For instance, Amazon Bedrock may augment the training dataset by generating similar prompts, effectively increasing the volume of the fine-tuning dataset.

Alternatively, it can produce high-quality teacher responses by using provided prompt-response pairs as golden examples. At preview, Amazon Bedrock Model Distillation supports Anthropic, Meta, and Amazon models.

Get started with Amazon Bedrock Model Distillation
To get started, go to the Amazon Bedrock console and choose Custom models in the left navigation pane. Now you have three customization methods: Fine-tuning, Distillation, and Continued pre-training.

Choose Create Distillation job to start fine-tuning your model using model distillation.

Enter your distilled model name and job name.

Then, choose the teacher model and, based on your choice of the teacher model, select a student model from the list of available student models. The teacher and the student model must be from the same family. For example, if you choose Meta Llama 3.1 405B Instruct model as a teacher model, you can only choose either Llama 3.1 70B or 8B Instruct model as a student model.

To generate synthetic data, set the value of Max response length, an inference parameter to determine the response generated by the teacher model. Choose the distillation input dataset located in your Amazon Simple Storage Service (Amazon S3) bucket. This input dataset presents the prompts or golden prompt-response pairs for your use case. The input files must be in the dataset format according to your model. To learn more, visit Prepare the datasets in the Amazon Bedrock User Guide.

Then, choose Create Distillation job after setting up the Amazon S3 location to store the distillation output metrics data and permissions to write to Amazon S3 on your behalf.

After the distillation job is created successfully, you can track the training progress on the Jobs tab, and the model will be available on the Models tab.

Using production data with Amazon Bedrock Model Distillation
If you want to reuse your production data for distillation and skip generating teacher responses again, you do so by turning on model invocation logging to collect invocation logs, model input data, and model output data for all invocations in your AWS account used in Amazon Bedrock. Adding request metadata helps you to easily filter invocation logs at a later point.

request_params = {
    'modelId': 'meta.llama3-1-405b-instruct-v1:0',
    'messages': [
        {
            'role': 'user',
            'content': [
                {
                    "text": "What is model distillation in generative AI?"
                }
            ]
        }
    },
    'requestMetadata': {
    "ProjectName": "myLlamaDistilledModel",
    "CodeName": "myDistilledCode"
    }
}
response = bedrock_runtime_client.converse(**request_params)
pprint(response)
---
'output': {'message': {'content': [{'text': '\n''\n'
    'Model distillation is a technique in generative AI that involves training a smaller,'
    'more efficient model (the '"student") to mimic the behavior of a larger, '
    'more complex model '(the "teacher"). The goal of model distillation is to'
    'transfer the knowledge and capabilities of the teacher model to the student model,'
    'allowing the student to perform similarly well on a given task, but with much less computational'
    'resources and memory.\n'
    '\n'}]
    }
}

Next, when using Amazon Bedrock Model Distillation, select a teacher model whose accuracy you want to aim for your use case and a student model that you want to fine-tune. Then give access to Amazon Bedrock to read your invocation logs. Here, you can specify the request metadata filters so that only specific logs, which are valid for your use case, are read to fine-tune the student model. The teacher model selected for distillation and the model used in the invocation logs must be the same if you want Amazon Bedrock to reuse the responses from invocation logs.

Inference from your distilled model
Before using the distilled model, you need to purchase Provisioned Throughput for Amazon Bedrock and then use the resulting distilled model for inference. When you purchase Provisioned Throughput, you can select a commitment term, choose the number of model units, and check estimated hourly, daily, and monthly costs.

You can complete the model distillation job using AWS APIs, AWS SDKs, or the AWS Command Line Interface (AWS CLI). To learn more about using the AWS CLI, visit Code samples for model customization in the AWS documentation.

Things to know
Here are a few important things to know.

  • Model distillation aims to increase the accuracy of the student model to match the performance of the teacher model for your specific use case. Before you begin model distillation, we recommend that you evaluate different teacher models for your use case and select the teacher model that works well for your use case.
  • We recommend optimizing your prompts for your use case against which you find the teacher model accuracy to be acceptable. Submit these prompts as the distillation input data.
  • To choose a corresponding student model to fine-tune, evaluate the latency profiles of different student model options for your use case. The final distilled model will have the same latency profile as the student model that you select.
  • If a specific student model already performs well for your use case, then we recommend using the student model as is instead of creating a distilled model.

Join the preview!
Amazon Bedrock Model Distillation is now available in preview in the US East (N. Virginia) and US West (Oregon) AWS Regions. Check the full Region list for future updates. To learn more, visit Model Distillation in the Amazon Bedrock User Guide.

You pay the cost to generate synthetic data by the teacher model and the cost to fine-tune the student model during model distillation. After the distilled model is created, you pay the cost to store the distilled model monthly. Inference from the distilled model is charged under Provisioned Throughput per hour per model unit. To learn more, visit the Amazon Bedrock Pricing page.

Give Amazon Bedrock Model Distillation a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

Channy

Introducing queryable object metadata for Amazon S3 buckets (preview)

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/introducing-queryable-object-metadata-for-amazon-s3-buckets-preview/

AWS customers make use of Amazon Simple Storage Service (Amazon S3) at an incredible scale, regularly creating individual buckets that contain billions or trillions of objects! At that scale, finding the objects which meet particular criteria — objects with keys that match a pattern, objects of a particular size, or objects with a specific tag — becomes challenging. Our customers have had to build systems that capture, store, and query for this information. These systems can become complex and hard to scale, and can fall out of sync with the actual state of the bucket and the objects within.

Rich Metadata
Today we are enabling in preview automatic generation of metadata that is captured when S3 objects are added or modified, and stored in fully managed Apache Iceberg tables. This allows you to use Iceberg-compatible tools such as Amazon Athena, Amazon Redshift, Amazon QuickSight, and Apache Spark to easily and efficiently query the metadata (and find the objects of interest) at any scale. As a result, you can quickly find the data that you need for your analytics, data processing, and AI training workloads.

For video inference responses stored in S3, Amazon Bedrock will annotate the content it generates with metadata that will allow you to identify the content as AI-generated, and to know which model was used to generate it.

The metadata schema contains over 20 elements including the bucket name, object key, creation/modification time, storage class, encryption status, tags, and user metadata. You can also store additional, application-specific descriptive information in a separate table and then join it with the metadata table as part of your query.

How it Works
You can enable capture of rich metadata for any of your S3 buckets by specifying the location (an S3 table bucket and a table name) where you want the metadata to be stored. Capture of updates (object creations, object deletions, and changes to object metadata) begins right away and will be stored in the table within minutes. Each update generates a new row in the table, with a record type (CREATE, UPDATE_METADATA, or DELETE) and a sequence number. You can retrieve the historical record for a given object by running a query that orders the results by sequence number.

Enabling and Querying Metadata
I start by creating a table bucket for my metadata using the create-table-bucket command (this can also be done from the AWS Management Console or with an API call):

$ aws s3tables create-table-bucket --name jbarr-table-bucket-1 --region us-east-2
--------------------------------------------------------------------------------
|                               CreateTableBucket                              |
+-----+------------------------------------------------------------------------+
|  arn|  arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-1   |
+-----+------------------------------------------------------------------------+

Then I specify the table bucket (by ARN) and the desired table name by putting this JSON into a file (I’ll call it config.json):

{
  "S3TablesDestination": {
    "TableBucketArn": "arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-1",
    "TableName": "jbarr_data_bucket_1_table"
  }
}

And then I attach this configuration to my data bucket (the one that I want to capture metadata for):

$ aws s3tables create-bucket-metadata-table-configuration \
  --bucket jbarr-data-bucket-1 \
  --metadata-table-configuration file://./config.json \
  --region us-east-2

For testing purposes I installed Apache Spark on an EC2 instance and after a little bit of setup I was able to run queries by referencing the Amazon S3 Tables Catalog for Apache Iceberg package and adding the metadata table (as mytablebucket) to the command line:

$ bin/spark-shell \
--packages org.apache.iceberg:iceberg-spark-runtime-3.4_2.12:1.6.0 \
--jars ~/S3TablesCatalog.jar \
--master yarn \
--conf "spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions" \
--conf "spark.sql.catalog.mytablebucket=org.apache.iceberg.spark.SparkCatalog" \
--conf "spark.sql.catalog.mytablebucket.catalog-impl=com.amazon.s3tables.iceberg.S3TablesCatalog" \
--conf "spark.sql.catalog.mytablebucket.warehouse=arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-1"

Here is the current schema for the Iceberg table:

scala> spark.sql("describe table mytablebucket.aws_s3_metadata.jbarr_data_bucket_1_table").show(100,35)

+---------------------+------------------+-----------------------------------+
|             col_name|         data_type|                            comment|
+---------------------+------------------+-----------------------------------+
|               bucket|            string|   The general purpose bucket name.|
|                  key|            string|The object key name (or key) tha...|
|      sequence_number|            string|The sequence number, which is an...|
|          record_type|            string|The type of this record, one of ...|
|     record_timestamp|     timestamp_ntz|The timestamp that's associated ...|
|           version_id|            string|The object's version ID. When yo...|
|     is_delete_marker|           boolean|The object's delete marker statu...|
|                 size|            bigint|The object size in bytes, not in...|
|   last_modified_date|     timestamp_ntz|The object creation date or the ...|
|                e_tag|            string|The entity tag (ETag), which is ...|
|        storage_class|            string|The storage class that's used fo...|
|         is_multipart|           boolean|The object's upload type. If the...|
|    encryption_status|            string|The object's server-side encrypt...|
|is_bucket_key_enabled|           boolean|The object's S3 Bucket Key enabl...|
|          kms_key_arn|            string|The Amazon Resource Name (ARN) f...|
|   checksum_algorithm|            string|The algorithm that's used to cre...|
|          object_tags|map<string,string>|The object tags that are associa...|
|        user_metadata|map<string,string>|The user metadata that's associa...|
|            requester|            string|The AWS account ID of the reques...|
|    source_ip_address|            string|The source IP address of the req...|
|           request_id|            string|The request ID. For records that...|
+---------------------+------------------+-----------------------------------+

Here’s a simple query that shows some of the metadata for the ten most recent updates:

scala> spark.sql("SELECT key,size, storage_class,encryption_status \
  FROM mytablebucket.aws_s3_metadata.jbarr_data_bucket_1_table \
  order by last_modified_date DESC LIMIT 10").show(false)
+--------------------+------+-------------+-----------------+                   
|key                 |size  |storage_class|encryption_status|
+--------------------+------+-------------+-----------------+
|wnt_itco_2.png      |36923 |STANDARD     |SSE-S3           |
|wnt_itco_1.png      |37274 |STANDARD     |SSE-S3           |
|wnt_imp_new_1.png   |15361 |STANDARD     |SSE-S3           |
|wnt_imp_change_3.png|67639 |STANDARD     |SSE-S3           |
|wnt_imp_change_2.png|67639 |STANDARD     |SSE-S3           |
|wnt_imp_change_1.png|71182 |STANDARD     |SSE-S3           |
|wnt_email_top_4.png |135164|STANDARD     |SSE-S3           |
|wnt_email_top_2.png |117171|STANDARD     |SSE-S3           |
|wnt_email_top_3.png |55913 |STANDARD     |SSE-S3           |
|wnt_email_top_1.png |140937|STANDARD     |SSE-S3           |
+--------------------+------+-------------+-----------------+

In a real-world situation I would query the table using one of the AWS or open source analytics tools that I mentioned earlier.

Console Access
I can also set up and manage the metadata configuration for my buckets using the Amazon S3 Console by clicking the Metadata tab:

Available Now
Amazon S3 Metadata is available in preview now and you can start using it today in the US East (Ohio, N. Virginia) and US West (Oregon) AWS Regions.

Integration with AWS Glue Data Catalog is in preview, allowing you to query and visualize data—including S3 Metadata tables—using AWS Analytics services such as Amazon Athena, Amazon Redshift, Amazon EMR, and Amazon QuickSight.

Pricing is based on the number updates (object creations, object deletions, and changes to object metadata) with an additional charge for storage of the metadata table. For more pricing information, visit the S3 Pricing page.

I’m confident that you will be able to make use of this metadata in many powerful ways, and am looking forward to hearing about your use cases. Let me know what you think!

Jeff;

New Amazon S3 Tables: Storage optimized for analytics workloads

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-amazon-s3-tables-storage-optimized-for-analytics-workloads/

Amazon S3 Tables give you storage that is optimized for tabular data such as daily purchase transactions, streaming sensor data, and ad impressions in Apache Iceberg format, for easy queries using popular query engines like Amazon Athena, Amazon EMR, and Apache Spark. When compared to self-managed table storage, you can expect up to 3x faster query performance and up to 10x more transactions per second, along with the operational efficiency that is part-and-parcel when you use a fully managed service.

Iceberg has become the most popular way to manage Parquet files, with thousands of AWS customers using Iceberg to query across often billions of files containing petabytes or even exabytes of data.

Table Buckets, Tables, and Namespaces
Table buckets are the third type of S3 bucket, taking their place alongside the existing general purpose and directory buckets. You can think of a table bucket as an analytics warehouse that can store Iceberg tables with various schemas. Additionally, S3 Tables deliver the same durability, availability, scalability, and performance characteristics as S3 itself, and automatically optimize your storage to maximize query performance and to minimize cost.

Each table bucket resides in a specific AWS Region and has a name that must be unique within the AWS account with respect to the region. Buckets are referenced by ARN and also have a resource policy. Finally, each bucket uses namespaces to logically group the tables in the bucket.

Tables are structured datasets stored in a table bucket. Like table buckets, they have ARNs and resource policies, and exist within one of the bucket’s namespaces. Tables are fully managed, with automatic, configurable continuous maintenance including compaction, management of aged snapshots, and removal of unreferenced files. Each table has an S3 API endpoint for storage operations.

Namespaces can be referenced from access policies in order to simplify access management.

Buckets and Tables from the Command Line
Ok, let’s dive right in, create a bucket, and put a table or two inside. I’ll use the AWS Command Line Interface (AWS CLI), but AWS Management Console and API support is also available. For conciseness, I will pipe the output of the more verbose commands through jq and show you only the most relevant values.

The first step is to create a table bucket:

$ aws s3tables create-table-bucket --name jbarr-table-bucket-2 | jq .arn
"arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-2"

For convenience, I create an environment variable with the ARN of the table bucket:

$ export ARN="arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-2"

And then I list my table buckets:

$ aws s3tables list-table-buckets | jq .tableBuckets[].arn
"arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-1"
"arn:aws:s3tables:us-east-2:123456789012:bucket/jbarr-table-bucket-2"

I can access and populate the table in many different ways. For testing purposes I installed Apache Spark, then invoked the Spark shell with command-line arguments to use the Amazon S3 Tables Catalog for Apache Iceberg package and to set mytablebucket to the ARN of my table.

I create a namespace (mydata) that I will use to group my tables:

scala> spark.sql("""CREATE NAMESPACE IF NOT EXISTS mytablebucket.mydata""")

Then I create a simple Iceberg table in the namespace:

spark.sql("""CREATE TABLE IF NOT EXISTS mytablebucket.mydata.table1
 (id INT,
  name STRING,
  value INT)
  USING iceberg
  """)

I use somes3tables commands to check my work:

$ aws s3tables list-namespaces --table-bucket-arn $ARN | jq .namespaces[].namespace[] 
"mydata"
$
$ aws s3tables list-tables --table-bucket-arn $ARN | jq .tables[].name
"table1"

Then I return to the Spark shell and add a few rows of data to my table:

spark.sql("""INSERT INTO mytablebucket.mydata.table1
  VALUES
  (1, 'Jeff', 100),
  (2, 'Carmen', 200),
  (3, 'Stephen', 300),
  (4, 'Andy', 400),
  (5, 'Tina', 500),
  (6, 'Bianca', 600),
  (7, 'Grace', 700)
  """)

Buckets and Tables from the Console
I can also create and work on table buckets using the S3 Console. I click Table buckets to get started:

Before creating my first bucket I click Enable integration so that I can access my table buckets from Amazon Athena, Amazon Redshift, Amazon EMR, and other AWS query engines (I can do this later if I don’t do it now):

I read the fine print and click Enable integration to create the specified IAM role and an entry in the AWS Glue Data Catalog:

After a few seconds the integration is enabled and I click Create table bucket to move ahead:

I enter a name (jbarr-table-bucket-3) and click Create table bucket:

From here I can create and use tables as I showed you earlier in the CLI section.

Table Maintenance
Table buckets take care of some important maintenance duties that would be your responsibility if you were creating and managing your own Iceberg tables. To relieve you of these duties so that you can spend more time on your table, the following maintenance operations are performed automatically:

Compaction – This process combines multiple small table objects into a larger object to improve query performance, in pursuit of a target file size that can be configured to be between 64 MiB and 512 MiB. The new object is rewritten as a new snapshot.

Snapshot Management – This process expires and ultimately removes table snapshots, with configuration options for the minimum number of snapshots to retain and the maximum age of a snapshot to retain. Expired snapshots are marked as non-current, then later deleted after a specified number of days.

Unreferenced File Removal – This process removes and deletes objects that are not referenced by any table snapshots.

Things to Know
Here are a couple of important things that you should know about table buckets and tables:

AWS Integration – S3 Tables integration with AWS Glue Data Catalog is in preview, allowing you to query and visualize data using AWS Analytics services such as Amazon Athena, Amazon Redshift, Amazon EMR, and Amazon QuickSight.

S3 API Support – Table buckets support relevant S3 API functions including GetObject, HeadObject, PutObject, and the multi-part upload operations.

Security – All objects stored in table buckets are automatically encrypted. Table buckets are configured to enforce Block Public Access.

Pricing – You pay for storage, requests, an object monitoring fee, and and fees for compaction. See the S3 Pricing page for more info.

Regions – You can use this new feature in the US East (Ohio, N. Virginia) and US West (Oregon) AWS Regions.

Jeff;

Amazon EC2 Trn2 Instances and Trn2 UltraServers for AI/ML training and inference are now available

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/amazon-ec2-trn2-instances-and-trn2-ultraservers-for-aiml-training-and-inference-is-now-available/

The new Amazon Elastic Compute Cloud (Amazon EC2) Trn2 instances and Trn2 UltraServers are the most powerful EC2 compute options for ML training and inference. Powered by the second generation of AWS Trainium chips (AWS Trainium2), the Trn2 instances are 4x faster, offer 4x more memory bandwidth, and 3x more memory capacity than the first-generation Trn1 instances. Trn2 instances offer 30-40% better price performance than the current generation of GPU-based EC2 P5e and P5en instances.

In addition to the 16 Trainium2 chips, each Trn2 instance features 192 vCPUs, 2 TiB of memory, and 3.2 Tbps of Elastic Fabric Adapter (EFA) v3 network bandwidth, which offers up to 50% lower latency than the previous generation.

The Trn2 UltraServers, which are a completely new compute offering, feature 64x Trainium2 chips connected with a high-bandwidth, low-latency NeuronLink interconnect, for peak inference and training performance on frontier foundation models.

Tens of thousands of Trainium chips are already powering Amazon and AWS services. For example, over 80,000 AWS Inferentia and Trainium1 chips supported the Rufus shopping assistant on the most recent Prime Day. Trainium2 chips are already powering the latency-optimized versions of Llama 3.1 405B and Claude 3.5 Haiku models on Amazon Bedrock.

Up and Out and Up
Sustained growth in the size and complexity of the frontier models is enabled by innovative forms of compute power, assembled into equally innovative architectural forms. In simpler times we could talk about architecting for scalability in two ways: scaling up (using a bigger computer) and scaling out (using more computers). Today, when I look at the Trainium2 chip, the Trn2 instance, and the even larger compute offerings that I will talk about in a minute, it seems like both models apply, but at different levels of the overall hierarchy. Let’s review the Trn2 building blocks, starting at the NeuronCore and scaling to an UltraCluster:

NeuronCores are at the heart of the Trainium2 chip. Each third-generation NeuronCore includes a scalar engine (1 input to 1 output), a vector engine (multiple inputs to multiple outputs), a tensor engine (systolic array multiplication, convolution, and transposition), and a GPSIMD (general purpose single instruction multiple data) core.

Each Trainium2 chip is home to eight NeuronCores and 96 GiB of High Bandwidth Memory (HBM), and supports 2.9 TB/second of HBM bandwidth. The cores can be addressed and used individually, or pairs of physical cores can be grouped into a single logical core. A single Trainium2 chip delivers up to 1.3 petaflops of dense FP8 compute and up to 5.2 petaflops of sparse FP8 compute, and can drive 95% utilization of memory bandwidth thanks to automated reordering of the HBM queue.

Each Trn2 instance is, in turn, home to 16 Trainum2 chips. That’s a total of 128 NeuronCores, 1.5 TiB of HBM, and 46 TB/second of HBM bandwidth. Altogether this multiplies out to up to 20.8 petaflops of dense FP8 compute and up to 83.2 petaflops of sparse FP8 compute. The Trainium2 chips are connected across NeuronLink in a 2D torus for high bandwidth, low latency chip-to-chip communication at 1 GB/second.

An UltraServer is home to four Trn2 instances connected with low-latency, high-bandwidth NeuronLink. That’s 512 NeuronCores, 64 Trainium2 chips, 6 TiB of HBM, and 185 TB/second of HBM bandwidth. Doing the math, this results in up to 83 petaflops of dense FP compute and up to 332 petaflops of sparse FP8 compute. In addition to the 2D torus that connects NeuronCores within an instance, Cores at corresponding XY positions in each of the four instances are connected in a ring. For inference, UltraServers help deliver industry-leading response time to create the best real-time experiences. For training, UltraServers boost model training speed and efficiency with faster collective communication for model parallelism when compared to standalone instances. UltraServers are designed to support training and inference at the trillion parameter level and beyond; they are available in preview form and you can contact us to join the preview.

Trn2 instances and UltraServers are being deployed in EC2 UltraClusters to enable scale-out distributed training across tens of thousands of Trainium chips on a single petabit scale, non-blocking network, with access to Amazon FSx for Lustre high performance storage.

Using Trn2 Instances
Trn2 instances are available today for production use in the US East (Ohio) AWS Region and can be reserved by using Amazon EC2 Capacity Blocks for ML. You can reserve up to 64 instances for up to six months, with reservations accepted up to eight weeks in advance, with instant start times and the ability to extend your reservations if needed. To learn more, read Announcing Amazon EC2 Capacity Blocks for ML to reserve GPU capacity for your machine learning workloads.

On the software side, you can start with the AWS Deep Learning AMIs. These images are preconfigured with the frameworks and tools that you probably already know and use: PyTorch, JAX, and a lot more.
If you used the AWS Neuron SDK to build your apps, you can bring them over and recompile them for use on Trn2 instances. This SDK integrates natively with JAX, PyTorch, and essential libraries like Hugging Face, PyTorch Lightning, and NeMo. Neuron includes out-of-the-box optimizations for distributed training and inference with the open source PyTorch libraries NxD Training and NxD Inference, while providing deep insights for profiling and debugging. Neuron also supports OpenXLA, including stable HLO and GSPMD, enabling PyTorch/XLA and JAX developers to utilize Neuron’s compiler optimizations for Trainium2.

Jeff;

Top announcements of AWS re:Invent 2024

Post Syndicated from AWS Editorial Team original https://aws.amazon.com/blogs/aws/top-announcements-of-aws-reinvent-2024/

AWS re:Invent 2024, our flagship anImage of large AWS logo with conference attendees moving in front of it in blurred motionnual conference, is taking place Dec. 2-6, 2024, in Las Vegas. This premier cloud computing event brings together the global cloud computing community for a week of keynotes, technical sessions, product launches, and networking opportunities. As AWS continues to unveil its latest innovations and services throughout the conference, we’ll keep you updated here with all the major product announcements.

Additional re:Invent resources:

  • AWS News Blog: Chief Evangelist Jeff Barr and colleagues keep you posted on the biggest and best new AWS offerings.
  • What’s New with AWS: A comprehensive list of all AWS launches.
  • The Official AWS Podcast: A podcast for developers and IT professionals looking for the latest news and trends from AWS.
  • AWS On Air: Live-streamed announcements and hands-on demos.
  • AWS re:Post: Join the community in conversation through Q&A.

(This post was last updated: 9:08 p.m. PST, Dec. 1, 2024.)


Quick category links:

AnalyticsApplication Integration | Business Applications | Compute | Containers | Database | Generative AI / Machine Learning | Management & Governance | Migration & Transfer Services | Security, Identity, & Compliance | Storage

Analytics

AWS Clean Rooms now supports multiple clouds and data sources
With expanded data sources, AWS Clean Rooms helps customers securely collaborate with their partners’ data across clouds, eliminating data movement, safeguarding sensitive information, promoting data freshness, and streamlining cross-company insights.

Application Integration

Securely share AWS resources across VPC and account boundaries with PrivateLink, VPC Lattice, EventBridge, and Step Functions

Orchestrate hybrid workflows accessing private HTTPS endpoints – no more Lambda/SQS workarounds. EventBridge and Step Functions natively support private resources, simplifying cloud modernization.


Business Applications

Newly enhanced Amazon Connect adds generative AI, WhatsApp Business, and secure data collection
Use innovative tools like generative AI for segmentation and campaigns, WhatsApp Business, data privacy controls for chat, AI guardrails, conversational AI bot management, and enhanced analytics to elevate customer experiences securely and efficiently.

Compute

Introducing storage optimized Amazon EC2 I8g instances powered by AWS Graviton4 processors and 3rd gen AWS Nitro SSDs
Elevate storage performance with AWS’s newest I8g instances, which deliver unparalleled speed and efficiency for I/O-intensive workloads.

Now available: Storage optimized Amazon EC2 I7ie instances
New AWS I7ie instances deliver unbeatable storage performance: up to 120TB NVMe, 40% better compute performance and up to 65% better real-time storage performance.

Containers

Use your on-premises infrastructure in Amazon EKS clusters with Amazon EKS Hybrid Nodes
Unify Kubernetes management across your cloud and on-premises environments with Amazon EKS Hybrid Nodes – use existing hardware while offloading control plane responsibilities to EKS for consistent operations.

Streamline Kubernetes cluster management with new Amazon EKS Auto Mode
With EKS Auto Mode, AWS simplifies Kubernetes cluster management, automating compute, storage, and networking, enabling higher agility and performance while reducing operational overhead.

Database

Amazon MemoryDB Multi-Region is now generally available
Build highly available, globally distributed apps with microsecond latencies across Regions, automatic conflict resolution, and up to 99.999% availability.

Generative AI / Machine Learning

New RAG evaluation and LLM-as-a-judge capabilities in Amazon Bedrock
Evaluate AI models and applications efficiently with Amazon Bedrock’s new LLM-as-a-judge capability for model evaluation and RAG evaluation for Knowledge Bases, offering a variety of quality and responsible AI metrics at scale.

Enhance your productivity with new extensions and integrations in Amazon Q Business
Seamlessly access AI assistance within work applications with Amazon Q Business’s new browser extensions and integrations.

New APIs in Amazon Bedrock to enhance RAG applications, now available
With custom connectors and reranking models, you can enhance RAG applications by enabling direct ingestion to knowledge bases without requiring a full sync, and improving response relevance through advanced reranking models.

Introducing new PartyRock capabilities and free daily usage
Unleash your creativity with PartyRock’s new AI capabilities: generate images, analyze visuals, search hundreds of thousands of apps, and process multiple docs simultaneously – no coding required.

Users can now query information embedded in various types of visuals, including diagrams, infographics, charts, and other image-based content.

Management & Governance

Container Insights with enhanced observability now available in Amazon ECS
With granular visibility into container workloads, CloudWatch Container Insights with enhanced observability for Amazon ECS enables proactive monitoring and faster troubleshooting, enhancing observability and improving application performance.

New Amazon CloudWatch Database Insights: Comprehensive database observability from fleets to instances
Monitor Amazon Aurora databases and gain comprehensive visibility into MySQL and PostgreSQL fleets and instances, analyze performance bottlenecks, track slow queries, set SLOs, and explore rich telemetry.

New Amazon CloudWatch and Amazon OpenSearch Service launch an integrated analytics experience
Unlock out-of-the-box OpenSearch dashboards and two additional query languages, OpenSearch SQL and PPL, for analyzing CloudWatch logs. OpenSearch customers can now analyze CloudWatch Logs without having to duplicate data.

Migration & Transfer Services

AWS Database Migration Service now automates time-intensive schema conversion tasks using generative AI
AWS DMS Schema Conversion converts up to 90% of your schema to accelerate your database migrations and reduce manual effort with the power of generative AI.

Announcing AWS Transfer Family web apps for fully managed Amazon S3 file transfers
AWS Transfer Family web apps are a new resource that you can use to create a simple interface for authorized line-of-business users to access data in Amazon S3 through a customizable web browser.

Introducing default data integrity protections for new objects in Amazon S3
Amazon S3 updates the default behavior of object upload requests with new data integrity protections that build upon S3’s existing durability posture.
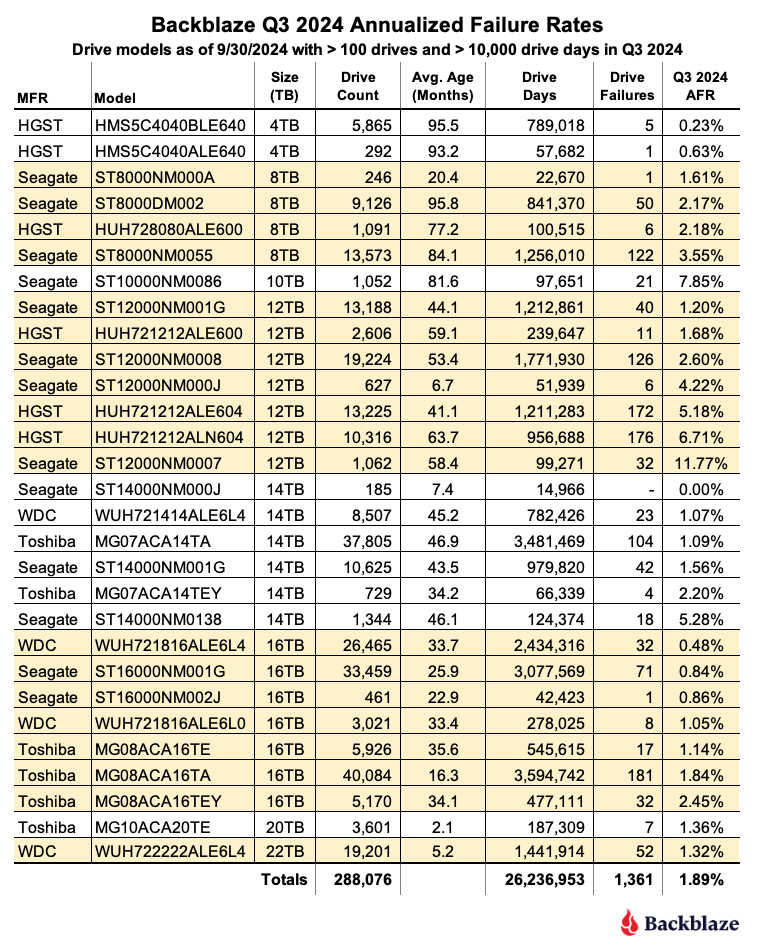
Security, Identity, & Compliance

New AWS Security Incident Response helps organizations respond to and recover from security events
AWS introduces a new service to streamline security event response, providing automated triage, coordinated communication, and expert guidance to recover from cybersecurity threats.

Introducing Amazon GuardDuty Extended Threat Detection: AI/ML attack sequence identification for enhanced cloud security
AWS extends GuardDuty with AI/ML capabilities to detect complex attack sequences across workloads, applications, and data, correlating multiple security signals over time for proactive cloud security.

Simplify governance with declarative policies
With only a few steps, create declarative policies and enforce desired configuration for AWS services across your organization, reducing ongoing governance overhead and providing transparency for administrators and end users.

AWS Verified Access now supports secure access to resources over non-HTTP(S) protocols (preview)
With only a few steps, create declarative policies and enforce desired configuration for AWS services across your organization, reducing ongoing governance overhead and providing transparency for administrators and end users.

Introducing Amazon OpenSearch Service and Amazon Security Lake integration to simplify security analytics
Analyze security logs without data duplication; Amazon OpenSearch Service now offers zero-ETL integration with Amazon Security Lake for efficient threat hunting and investigations.

Storage

Announcing Amazon FSx Intelligent-Tiering, a new storage class for FSx for OpenZFS
Delivering NAS capabilities with automatic data tiering among frequently accessed, infrequent, and archival storage tiers, Amazon FSx Intelligent-Tiering offers high performance up to 400K IOPS, 20 GB/s throughput, seamless integration with AWS services.

New physical AWS Data Transfer Terminals let you upload to the cloud faster
Rapidly upload large datasets to AWS at blazing speeds with the new AWS Data Transfer Terminal, secure physical locations offering high throughput connection.

Connect users to data through your apps with Storage Browser for Amazon S3
Storage Browser for Amazon S3 is an open source interface component that you can add to your web applications to provide your authorized end users, such as customers, partners, and employees, with access to easily browse, upload, download, copy, and delete data in S3.

5 Ways to Use Event Notifications to Advance Your Media Better, Faster

Post Syndicated from Jeremy Milk original https://www.backblaze.com/blog/5-ways-to-use-event-notifications-to-advance-your-media-better-faster/

A decorative image showing a cloud with digital lines and media icons.

In the hurry-up-and-wait world of media production, anything you can do to speed through the hurry-ups and avoid or shorten the waits is not just a gift—it’s an advantage that can mean happier team members, delighted clients and fans, and more revenue.

Backblaze Event Notifications can help.This new B2 Cloud Storage feature can help you streamline a range of your production tasks—like automatically starting transcoding of video and distributing new images—across your preferred workflow tools. 

Today, I’m sharing five ways you can use Backblaze Event Notifications to operationalize media production efficiencies. If you’re interested in Event Notifications for applications, check out this post; and stay tuned for a future post on how to use Event Notifications for IT backup.

Event Notifications for media production: Simplified automation

Event Notifications monitors your B2 Cloud Storage for data changes that you designate—think raw video uploads, content version updates, deletions, etc.—and delivers near real-time alerts where you want them about these changes. These alerts can be used to create awareness faster, and even more powerfully, to initiate streamlined end-to-end processes that can save you time and hassle, and avoid unnecessary manual tasks and/or the cost of complex intermediaries.

What are webhooks?

Webhooks, if you’re not familiar with the term, are HTTP-based callback functions that enable event-based communications between software applications. Backblaze Event Notifications can uniquely work with any external service that accepts webhooks. This means you can use it to your advantage across your media production workflow—and this is novel when most vendors’ alerts features are limited to closed ecosystems or require significant and sometimes costly workarounds to communicate beyond a limited set of production tools.

Top 5 use cases for media production

Here are specific, practical ways people producing and managing media can take advantage of Event Notifications for immediate benefits.

1. New content processing

Event Notifications can be used to trigger tasks immediately after new content is uploaded. Imagine one of your team members uploads a video or image: Event Notifications can be sent to a transcoding service to format it and a tagging service to categorize it for better content organization. Set up to furthermore extract valuable metadata too—all in near real time, without manual intervention. 

General workflow (abbreviated)

By automating these processes, companies can ensure that user-generated content is formatted correctly, appropriately tagged, and moderated without delay. This not only saves time but guarantees a consistent user experience.

What’s more, you can even go full Jedi Knight and handle errors programmatically with Event Notifications logic that triggers reprocessing tasks whenever issues arise.

2. Integrated alerts in go-to tools

Event Notifications can easily integrate with your communication tools like Slack and productivity tools like Zapier, to inform internal and external stakeholders of updates without them needing to check for them manually. Users have told us this is a great way to keep people updated when assets are added, updated, or advanced to key stages in production and post cycles—setting them up to consider taking downstream actions that don’t lend themselves to further process automation.

Asset change announcement workflow

Additionally, for teams using workflow tools such as Zapier to connect various services, Event Notifications makes it simple to trigger actions across multiple platforms, enabling powerful, automated workflows with your data in B2 Cloud Storage.

3. Over-the-top (OTT) streaming automation

Regardless of whether your streaming model is AVOD, TVOD, or SVOD, Event Notifications can help automate processing and distribution workflows. Users can enable them so that every time a new title is added to B2 Cloud Storage, it then triggers alerts that initiate transcoding, compression, and prep for delivery or playback via content delivery network (CDN).

OTT streaming platform workflow

4. Backup completion monitoring

An important (if unglamorous) aspect of managing media is backing it up for extra safekeeping. After all, it’s a precious asset worth a lot of money now and later. So whether you back up nightly, monthly, at project’s end, or on some other cadence, with Event Notifications, customers can set up to receive updates when their media backups are successfully uploaded to a Backblaze B2 Bucket—providing peace of mind when data is protected.

We’ve also had a few users already tell us that not seeing backup completion alerts when expected helped them realize that they had other, previously unknown workflow hiccups to address.

Backup complete workflow

Tangentially related, media organizations are also using Backblaze Cloud Replication to programmatically store their content to two or more geographically distributed locations for added protection—this isn’t the same as Event Notifications, but is another automation tool for enhancing your protection posture.

5. Monitor data usage

Since Event Notifications messages are sent within seconds of files being uploaded and deleted, and they contain the size of the file in question, you can easily and reliably track your data usage in near real time, helping you identify trends and potential issues. For example, if you know large raw files are coming in and then messages indicating much smaller than expected file sizes were uploaded, it can alert you to begin to QC it.

We’ve also seen such data monitoring prove highly beneficial to IT personnel who support them because the near real-time monitoring allows faster responses to situations as they are happening, thereby mitigating risks, reducing costs, and/or nipping issues in the bud so the production teams remain disruption and distraction free.

Monitoring workflow

Beyond these example use cases, Event Notifications opens up a wide range of possibilities for automating and optimizing workflows. This flexibility makes it easy to automate how your infrastructure interacts with and reacts to file changes in B2 Cloud Storage, simplifying workflows across your distributed services. So go ahead and get creative—and please do share with us the cool things you’re doing with Event Notifications.

Why Event Notifications matter for production workflows

The benefits of real-time notifications extend beyond simply saving time—they transform the way teams work, automate processes, and reduce the margin for error.

  • Awareness: Instant notifications for uploads, updates, or deletions keep everyone on the same page.
  • Actionable insights: Real-time alerts provide critical information that helps make informed decisions quickly.
  • Flexibility: Direct connections to services like media asset managers (MAMs), transcoding applications, and CDNs mean more choice to stick with your preferred stack and less lock-in to specific vendors or tools.
  • Cost efficiency: Automating tasks like media transcoding, data processing, or content delivery reduces the need for manual labor, saving on operational costs and freeing up resources for other strategic initiatives.

Improved security: By instantly alerting teams to changes or unusual activity, Event Notifications help maintain data integrity and support proactive security measures.

How Event Notifications compares

Unlike other offerings like Amazon’s messaging services, which are limited to specific ecosystems, Backblaze Event Notifications integrates directly with any service that accepts webhooks, offering true flexibility and avoiding vendor lock-in.

Event Notifications is also designed for at-least-once delivery, ensuring critical notifications are not missed. This reliability is important for teams building workflows that require precision and a level of consistency their end users expect. 

The pricing for Event Notifications is simple and transparent. Backblaze B2 Reserve customers enjoy unlimited free Event Notifications, while pay-as-you-go Backblaze B2 customers enjoy 2,500 calls per day free and then $0.004 per 10,000 transactions. This straightforward pricing applies no matter the service receiving the notification. This enables businesses to confidently scale their event-driven workflows, knowing exactly what to expect in terms of costs, regardless of the services they choose to integrate with. 

Ready to add automation to your media tasks?

For existing customers working with a Backblaze account manager, Event Notifications is already enabled for you, and your account manager can assist with any questions. If you’re an existing customer not currently working with an account manager, please contact our Support team to request access to Event Notifications. 

New customers can contact our Sales team to learn more about how Event Notifications can streamline workflows and how to get started.

Once Event Notifications are enabled, log in to your Backblaze B2 account, navigate to the Buckets page, and click on the Event Notifications section. From there, you can set up notification rules for the events you want to track or configure notifications using our API.

For detailed instructions and best practices, visit our Event Notifications documentation.

The post 5 Ways to Use Event Notifications to Advance Your Media Better, Faster appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Holiday Gift Guide 2024

Post Syndicated from Yev original https://www.backblaze.com/blog/holiday-gift-guide-2024/

A decorative image showing a gift floating in the ether, waiting to be given.

Ah, the holidays. They can be both fun and stressful for many of us—not least because we have to make so many decisions around gift giving. The plethora of cyber sales and new products on the market make this a great time to try out new products yourself or buy some for the loved people in your lives. To that end, I’ve followed tradition and asked some of my fellow Backblazers to submit their gift ideas for this year and we’ve compiled them into this 2024 gift giving list!

Reading, (w)righting, (a)rithmatic

Kindle Paperwhite

A product image of the Kindle Paperwhite.

For the reader in your life, the Kindle Paperwhite is a great way to keep reading regardless of the conditions. It uses e-ink technology to avoid glare and allows for reading in both high and low light conditions!

ReMarkable Paper Pro

A product image of the ReMarkable Paper Pro.

This is one of the coolest devices out there, and I can personally say that I desperately want someone to gift me one (although it’s a bit on the pricey side, so I get it). This uses similar e-ink technology as the Paperwhite and allows you to take notes using your own handwriting—which (at least in my case when I write in cursive) helps me remember things!

Tekfun LCD Writing and Doodle Tablet

A product image of a Tekfun LCD Writing and Doodle Tablet.

Mixing writing and artistry, this doodle tablet is great for kiddos that are with you in a restaurant or long-haul flight. In fact, I just bought one of these for my nephew!

Klein Bottle

A product image of a Klein bottle.

Some people are math people. I don’t get it, but this Klein Bottle is basically an inside joke to math nerds (something about Möbius loops) and can serve as a lovely table prop for the math lover in your life.

Sounds good!

HyperX Cloud Alpha Wireless Gaming Headset

A product image of the HyperX Cloud Alpha wireless gaming headset.

For the gamer in your life, these are some of the best headphones on the market. They’re wireless, they sound great, and the microphone picks up all of the positive (I’m sure) feedback for teammates.

Apple AirPods 4

A product image of the Apple AirPods 4.

The latest and greatest from Apple. These come with a new chip that helps with transparency mode so you can cross the street with confidence.

Google Pixel Buds Pro 2

A product image of the Pixel Buds Pro 2.

If you’re an Android user (raises hand) you may want something built for your phone and the latest Pro version of the Pixel Buds are here for you. These come with little nubs for snug fit, meaning you can run or lift or meander without worrying that your tiny buds will fall out.

Experiences

Sur La Table Cooking Classes

A screenshot form the Sur La Table website that features their holiday cooking classes.

Who doesn’t want to impress loved ones with delicious dishes? If you have a Sur La Table near you, these are great.

Airbnb Experiences

An image showing the AirBnB experiences logo as well as some images from destinations.

If you’re a fan of traveling you’ve likely stayed at an AirBnB. But even if you’re more of a homebase person, their Experiences tab is worth checking out. From cooking to glass blowing to cow cuddle therapy (yes, that’s a thing).

Odds and ends

theFube Fidget Cube

A product image of theFube Fidget Cube.

I have one of these in my car and, let me tell you, as a person who used to bite their nails out of boredom (gross, I know), it helps keep my mind and compulsions at bay! Highly recommend.

Under Desk Foot Rest

A product image of an under desk foot rest.

Many of us spend our day sitting, sometimes standing at a desk. Even when you’re sitting, though, ergonomics are a big deal and having an adjustable foot rest can help you get into a position that feels solid and sustainable for long stretches of time. I recommend getting up and stretching every now and again, but if you’re like me and have a bad back, these are great.

Leatherman ARC

A product image of a Leatherman Arc.

Whether you’re outdoors or indoors, sometimes you need to cut or saw or screw or open or pry or file something, and for that, these Leatherman tools cannot be beaten.

Give the gift of Backblaze

And, of course, we’d be remiss if we didn’t remind you that Backblaze Computer Backup makes a great gift. Help your family and friends experience the sweet, sweet peace of mind that comes from a good backup strategy and make sure they never lose a file again. Bonus: you don’t even have to go to the store to get it.

A decorative showing a gift covered in Backblaze logos.

Go forth and gift!

We hope this guide sparked some ideas and simplified some choices. We love hearing about what folks are excited about, so feel free to give us some more good options in the comments below.

The post Holiday Gift Guide 2024 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

7 Ways to Use Event Notifications to Streamline Application Workflows

Post Syndicated from Amrit Singh original https://www.backblaze.com/blog/7-ways-to-use-event-notifications-to-streamline-application-workflows/

A decorative image showing a cloud with an alert symbol.

Event-driven infrastructure is at the core of modern application development. It helps businesses streamline processes like transcoding user-uploaded video or processing images for tagging, kicks off downstream workflows immediately, and reduces complexity by automating multi-step processes across distributed services. 

Today, I’m sharing seven ways you can use Backblaze Event Notifications to accelerate application workflows, automate processes, streamline operations, and scale revenue. If you’re interested in Event Notifications, but you’re not using it to run applications, stay tuned for future posts sharing use cases for media management and backup and archive. 

Event Notifications for applications: Simplified automation

Event Notifications delivers near real-time alerts for changes in B2 Cloud Storage, simplifying workflows across the services that interact with your stored data. Teams can use Event Notifications to create end-to-end processes that scale efficiently and integrate directly with any external service that accepts webhooks. This means no more manual monitoring of storage or relying on complex intermediaries.

What are webhooks?

Webhooks, if you’re not familiar, are a way for applications to communicate with each other by sending data automatically based on specific events, e.g., HTTP POST requests with a JSON payload. Notably, our Event Notifications feature isn’t limited to a closed ecosystem or subset of business tools.

Automating common application tasks with Event Notifications allows you to reduce operational overhead by minimizing manual monitoring, accelerate processes across integrations with your preferred services, and reduce manual entry errors that can cost enterprises time and money. 

Top 7 use cases for applications

Let’s explore some practical ways Event Notifications can be leveraged within your tech stack:

1. User-generated content processing

For applications dealing with user-uploaded content, Event Notifications can be used to trigger tasks immediately upon data upload. Imagine a user uploading a video or image: An Event Notification could be sent to a transcoding service to format it, a tagging service to categorize it, or even a moderation tool to ensure it complies with your community standards—all in near real time, without manual intervention.

Social platform workflow

By automating these processes, companies can ensure that user-generated content is formatted correctly, appropriately tagged, and moderated without delay. This not only saves time but guarantees a consistent user experience. 

2. Integrated alerts with automation tools

Event Notifications can easily integrate with productivity tools like Slack and Zapier, or any service that accepts a webhook, making it easy to provide team-wide awareness into changes in your storage environment without manual checks. This keeps teams informed and at the ready to be able to respond immediately to critical events.

Asset tracking and monitoring workflow

Additionally, for teams using workflow platforms such as Zapier to connect various services, Event Notifications makes it simple to trigger actions across multiple platforms, enabling powerful, automated workflows with your data in B2 Cloud Storage.

3. Surveillance and streaming automation

For applications managing large video files, such as surveillance or streaming platforms, Event Notifications can help automate the processing and distribution workflows. Videos can be transcoded, compressed, and prepared for delivery or playback promptly.

Streaming platform workflow

This automation is also useful for time-sensitive content, where quick turnaround is essential. Automating video processing reduces the manual effort involved and ensures content is always ready for viewing in the preferred format as soon as it’s available.

4. AI workload automation

For businesses building AI applications, Event Notifications can be used to trigger AI workloads in real time, enabling faster processing and response. For instance, when new data is uploaded, alerts can trigger downstream services to process that data, such as converting images to text or analyzing content for insights. 

AI image to text workflow

In this case, this AI workflow ensures tasks start the moment data becomes available. Whether you’re running an image recognition service, analyzing datasets, or building AI models, Event Notifications eliminates the delays that come with manual processing. No matter what your downstream service is, Event Notifications provides the flexibility to integrate seamlessly with your AI workflows, improving real-time processing capabilities and enabling teams to focus on delivering better solutions rather than managing manual data flow.

5. Monitor data usage

Since Event Notifications messages are sent within seconds of files being uploaded and deleted, and contain the size of the file in question, you can easily and reliably track your data usage in near real time, helping you identify trends and potential issues.

Monitoring workflow

In contrast with periodic usage reports, near real-time monitoring allows you to respond to situations as they are happening, mitigating risks and potentially reducing costs.

6. Respond to security events

Event Notifications can feed near real-time data to security information and event management (SIEM) systems, allowing you to detect and respond to anomalous access patterns as they are happening.

Security alert workflow

Event Notifications allows you to take a proactive, rather than reactive, security posture, again mitigating risks and reducing costs.

7. Automatically trigger data integration

Event Notifications enable your data integration workloads to run within seconds of new data being uploaded to Backblaze B2, continuously delivering data to analytical systems and dashboards, giving you a live view of the state of your business.

Data integration workflow

Delivering data to dashboards within seconds or minutes of its availability enables near real-time insights, faster decision-making, and the ability to react to events as they occur.

Beyond these example use cases, Event Notifications opens up a wide range of possibilities for automating and optimizing workflows. You can use Event Notifications to automate metadata extraction and tagging for better content organization, and handle errors programmatically by triggering reprocessing tasks whenever issues arise. This flexibility makes it easy to automate how your infrastructure interacts with and reacts to data changes in B2 Cloud Storage, simplifying workflows across your distributed services.

Why Event Notifications matter for application workflows

The benefits of real-time notifications extend beyond simply saving time—they transform the way teams work, automate processes, and reduce the margin for error.

  • Awareness: Instant notifications for data changes, uploads, or deletions keep everyone on the same page.
  • Actionable insights: Whether it’s confirming a successful upload or catching an unexpected change, real-time alerts provide critical information that helps make informed decisions quickly.
  • Flexibility: Direct connections to services like transcoding, compute, or serverless applications mean more choice and less lock-in to specific vendors or tools.
  • Improved security: By instantly alerting teams to unauthorized changes or unusual activity, Event Notifications help maintain data integrity and support proactive security measures.
  • Cost efficiency: Automating tasks like media transcoding, data processing, or content delivery reduces the need for manual labor, saving on operational costs and freeing up resources for other strategic initiatives.

How Event Notifications compares

Unlike other offerings like Amazon’s messaging services, which are limited to specific ecosystems, Event Notifications integrates directly with any service that accepts webhooks, offering true flexibility and avoiding vendor lock-in.

Event Notifications is also designed for at-least-once delivery, ensuring critical notifications are not missed. This reliability is important for teams building workflows that require precision and a level of consistency their end users expect. 

The pricing for Event Notifications is simple and transparent, with 2,500 calls per day free, and just $0.004 per 10,000 transactions. This straightforward pricing applies no matter the service receiving the notification. This enables businesses to confidently scale their event-driven workflows, knowing exactly what to expect in terms of costs, regardless of the services they choose to integrate with. 

Ready to add automation to your application?

For existing customers working with a Backblaze account manager, Event Notifications is already enabled for you, and your account manager can assist with any questions. If you’re an existing customer not currently working with an account manager, please contact our Support team to request access to Event Notifications. 

New customers can contact our Sales team to learn more about how Event Notifications can streamline workflows and how to get started.

Once Event Notifications are enabled, log in to your Backblaze B2 account, navigate to the Buckets page, and click on the Event Notifications section. From there, you can set up notification rules for the events you want to track or configure notifications using our API.

For detailed instructions and best practices, visit our Event Notifications documentation.

The post 7 Ways to Use Event Notifications to Streamline Application Workflows appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Introducing resource control policies (RCPs), a new type of authorization policy in AWS Organizations

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/introducing-resource-control-policies-rcps-a-new-authorization-policy/

Today, I am happy to introduce resource control policies (RCPs) – a new authorization policy managed in AWS Organizations that can be used to set the maximum available permissions on resources within your entire organization. They are a type of preventative control that help you establish a data perimeter in your AWS environment and restrict external access to resources at scale. Enforced centrally within Organizations, RCPs provide confidence to the central governance and security teams that access to resources within their AWS accounts conforms to their organization’s access control guidelines.

RCPs are available in all commercial AWS Regions and, at launch, the following services are supported: Amazon Simple Storage Service (Amazon S3), AWS Security Token Service (AWS STS), AWS Key Management Service (AWS KMS), Amazon Simple Queue Service (Amazon SQS), and AWS Secrets Manager.

There are no additional charges for enabling and using RCPs.

How are they different from service control policies (SCPs)?
While similar in nature, RCPs complement service control policies (SCPs), but they work independently.

Service control policies (SCPs) allow you to limit the permissions granted to principals within your organization such as AWS Identity and Access Management (IAM) roles. By constraining these permissions centrally within Organizations you can restrict access to AWS services, specific resources and even under what conditions principals can make requests across multiple AWS accounts.

RCPs, on the other hand, allow you to limit the permissions granted to resources in your organization. Because you implement RCPs centrally within Organizations, you can enforce consistent access controls on resources across multiple AWS accounts. For instance, you can restrict access to S3 buckets in your accounts so that they can only be accessed by principals that belong to your organization. RCPs are evaluated when your resources are being accessed irrespective of who is making the API request.

Keep in mind that neither SCPs nor RCPs grant any permissions. They only set the maximum permissions available to principals and resources in your organization. You still need to grant permissions with appropriate IAM policies, such as identity-based or resource-based policies.

Quotas for SCPs and RCPs are completely independent from each other. Each RCP can contain up to 5,120 characters. You can have up to five RCPs attached to the organization root, each OU, and account, and you can create and store up to 1000 RCPs in an organization.

How to get started
To start using RCPs you must first enable them. You can do this using the Organizations console, an AWS SDK, or by using the AWS Command Line Interface (AWS CLI). Make sure you are using the Organizations management account or a delegated administrator because those are the only accounts that can enable or disable policy types.

Make sure that you are using Organizations with the “all features” option. If you are using the “Consolidated billing features” mode, then you need to migrate to using all features before you can enable RCPs.

For console users, first head to the Organizations console. Choose Policies and you should see the option to enable Resource control policies.

enabling RCPs in the AWS Organizations console

After RCPs are enabled, you will notice in the Resource control policies page that a new policy called RCPFullAWSAccess is now available. This is an AWS managed policy that is automatically created and attached to every entity in your organization including the root, each OU, and AWS account.

the RCPFullAWSAccessPolicy can be seen on the console once RCPs are enabled

This policy allows all principals to perform any action against the organization’s resources, which means that until you start creating and attaching your own RCPs, all of your existing IAM permissions continue to operate as they did.

This is how it looks:

{
  "Version": "2012-10-17",
  "Statement": [
    { 
        "Effect": "Allow", 
        "Principal": "*", 
        "Action": "*", 
        "Resource": "*" 
    }
  ]
}

Creating an RCP

Now, we are ready to create our first RCP! Let’s look at an example.

By default, AWS resources do not permit access to external principals; resource owners must explicitly grant such access by configuring their policies. While developers have the flexibility to set resource-based policies according to their application needs, RCPs enable central IT teams to maintain control over the effective permissions across resources in their organization. This ensures that even if developers grant broad access, external identities are still restricted access in accordance with the organization’s security requirements.

Let’s create an RCP to restrict access to our S3 buckets so that only principals within our organization can access them.

On the Resources control policies page, choose Create policy which will take you to the page where you can author a new policy.

create a new resource control policy pageI am going to call this policy EnforceOrgIdentities. I recommend you enter a clear description so it is easy to understand at first glance what this policy does and to tag it appropriately.

The next section is where you can edit your policy statement. I replace the pre-populated policy template with my own:

create policy - policy syntaxHere is the full JSON policy document:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "EnforceOrgIdentities",
            "Effect": "Deny",
            "Principal": "*",
            "Action": "s3:*",
            "Resource": "*",
            "Condition": {
                "StringNotEqualsIfExists": {
                    "aws:PrincipalOrgID": "[MY ORG ID]"
                },
                "BoolIfExists": {
                    "aws:PrincipalIsAWSService": "false"
                }
            }
        }
    ]
}

Let’s break this down:

Version – This is a standard and required element of IAM policies. AWS maintains backwards compatibility, so using the latest version, currently 2012-10-17, doesn’t break existing policies but allows you to use newer features.

Statement – An array that can contain one or more statement objects. Each of these statement objects defines a single permission or set of permissions.

Sid – This is an optional field that can be helpful for policy management and troubleshooting. It needs to be unique within the scope of this JSON policy document.

Effect – As you might remember from earlier, by default we have an RCP that allows access to every AWS principal, action, and resource attached to every entity in our organization. Therefore, you should use Deny to apply restrictions.

Principal – For an RCP, this field must always be set to "*". Use the Condition field if you want this policy to apply only to specific principals.

Action – Specifies the AWS service and the actions that this policy applies to. In this case, we want to deny all interactions with Amazon S3 if they don’t meet our access control guidelines.

Resource – Specifies the resources that the RCP applies to.

Condition – A collection of conditions that will be evaluated to determine whether the policy should be applied or not for each request.

It’s important to remember that all conditions must evaluate to true for the RCP to be applied. In this case, we are applying two conditions:

1. Was the request made by an external principal?

"StringNotEqualsIfExists": 
 { 
   "aws:PrincipalOrgID": "[MY ORG ID]" 
 }

This condition first checks if the key aws:PrincipalOrgID is present in the request. If it’s not, then this condition evaluates to true without further evaluation.

If it does exist, then it compares the value to our organization ID. If the value is the same then it evaluates to false which means that the RCP will not be applied because all conditions must evaluate to true. This is the intended behaviour because we don’t want to deny access to principals within our organization.

However, if the value doesn’t match our organization ID, that means the request was made by a principal who is external to our organization. The condition evaluates to true which means that the RCP can still potentially be applied as long as the second condition also evaluates to true.

2. Is the request coming from an AWS service?

"BoolIfExists": 
   { 
     "aws:PrincipalIsAWSService": "false"
   }

This condition tests if the request contains a special key called aws:PrincipalIsAWSService which is automatically injected into the request context for all signed API requests and is set to true when it originates from an AWS service such as AWS CloudTrail writing events to your S3 bucket. If the key is not present, then this condition evaluates to true.

If it does exist, then it will compare the value to what we declare in our statement. In this case, we are testing if the value is equal to false. If it is, then we return true since that would mean that the request was not made by an AWS service and could potentially still have been made by someone outside of our organization. Otherwise, we return false.

In other words, if the request did not originate from a principal within our organization and it did not originate from an AWS service, then access to the S3 bucket is denied.

This policy is just a sample and you should tailor it to meet your unique business and security objectives. For instance, you might want to customize this policy to allow access by your business partners or to restrict access to AWS services so that they can access your resources only on your behalf. See Establishing a data perimeter on AWS: Allow only trusted identities to access company data for more details.

Attaching an RCP
The process of attaching an RCP is similar to an SCP. As previously mentioned, you can attach it to the root of your organization, to an OU, or to specific AWS accounts within your organization.

attaching a policy

After the RCP is attached, access requests to affected AWS resources must comply with the RCP restrictions. We recommend that you thoroughly test the impact that the RCP has on resources in your accounts before enforcing it at scale. You can begin by attaching RCPs to individual test accounts or test OUs.

Seeing it in action
I have now created and attached my RCP, so I’m ready to see it in practice! Let’s assume that a developer attached a resource-based policy to an S3 bucket in our organization and they explicitly gave access to identities in an external account:

bucket policy with external account id

RCPs do not prevent users from saving resource-based policies that are more permissive than the RCP allows. However, the RCP will be evaluated as part of the authorization process, as we’ve seen previously, so the request by external identities will be denied regardless.

We can prove this by trying to access the bucket with this external account, this time from the AWS CLI:


$ aws s3api get-object —bucket 123124ffeiufskdjfgbwer \
  --key sensitivefile.txt \
  --region us-east-1 local_file

An error occurred (AccessDenied) when calling the GetObject operation: Access Denied

Scaling the deployment of RCPs in your environment
So far, we have seen how we can manage RCPs using the console. However, for large-scale control management you should look into configuring them as infrastructure as code and make sure they are integrated into your existing continuous integration and continuous delivery (CI/CD) pipelines and processes.

If you use AWS Control Tower, you can deploy RCP-based controls in addition to SCP-based controls. For instance, you can use AWS Control Tower to deploy an RCP similar to that we created in the preceding example which prevents external principals from accessing S3 buckets in our organization. This ensures that RCPs are consistently applied to resources in managed accounts, streamlining and centralizing access control governance at scale.

Additionally, similar to SCPs, AWS Control Tower also supports drift detection for RCPs. If an RCP is modified or removed outside of AWS Control Tower, you will be notified of the drift and provided with steps for remediation.

Conclusion
Resource control policies (RCPs) offer centralized management over the maximum permissions available to AWS resources in your organization. Along with SCPs, RCPs help you to centrally establish a data perimeter across your AWS environment and prevent unintended access at scale. SCPs and RCPs are independent controls that allow you to achieve a distinct set of security objectives. You can choose to enable only SCPs or RCPs, or use both policy types together to establish a comprehensive security baseline as part of the defense-in-depth security model.

To learn more, see Resource control policies (RCPs) in the AWS Organizations User Guide.

Matheus Guimaraes | @codingmatheus

Backblaze Drive Stats for Q3 2024

Post Syndicated from Andy Klein original https://www.backblaze.com/blog/backblaze-drive-stats-for-q3-2024/

A decorative image that displays the words Q3 2024 Drive Stats.

As of the end of Q3 2024, Backblaze was monitoring 292,647 hard disk drives (HDDs) and solid state drives (SSDs) in our cloud storage servers located in our data centers around the world. We removed from this analysis 4,100 boot drives, consisting of 3,344 SSDs and 756 HDDs. This leaves us with 288,547 hard drives under management to review for this report. We’ll review the annualized failure rates (AFRs) for Q3 2024 and the lifetime AFRs of the qualifying drive models. Along the way, we’ll share our observations and insights on the data presented and, as always, we look forward to you doing the same in the comments section at the end of the post.

Hard drive failure rates for Q3 2024

For our Q3 2024 quarterly analysis, we remove the following from consideration: drive models which did not have at least 100 drives in service at the end of the quarter, drive models which did not accumulate 10,000 or more drive days during the quarter, and individual drives which exceeded their manufacturer’s temperature specification during their lifetime. The removed pool totalled 471 drives, leaving us with 288,076 drives grouped into 29 drive models for our Q3 2024 analysis. 

The table below lists the AFRs and related data for these drive models. The table is sorted ascending by drive size then ascending by AFR within drive size.

Notes and observations on the Q3 2024 Drive Stats

  • Upward AFR. The quarter-to-quarter AFR continues to creep up rising from 1.71% in Q2 2024 to 1.89% in Q3 2024. The rise can’t be attributed to the aging 4TB drives, as our CVT drive migration system continues to replace these drives. As a consequence, the AFR for the remaining 4TB drives was 0.26% in Q3. The primary culprit is the collection of 8TB drives, which are now on average over seven years old. As a group, the AFR for the 8TB drives rose to 3.04% in Q3 2024, up from 2.31% in Q2. The CVT team is gearing up to begin the migration of 8TB drives over the next few months.
  • Yet another golden oldie is gone. You may have noticed that the 4TB Seagate drives (model: ST4000DM000) are missing from the table. All of the Backblaze Vaults containing these drives have been migrated, and as a consequence there are only two of these drives remaining, not enough to make the quarterly chart. You can read more about their demise in our recent Halloween post. 
  • A new drive in town. In Q3, the 20TB Toshiba drives (model: MG10ACA20TE) arrived in force, populating three complete Backblaze Vaults of 1,200 drives each. Over the last few months our drive qualification team put the 20TB drive model through its paces and, having passed the test, they are now on the list of drive models we can deploy.
  • One zero. For the second quarter in a row, the 14TB Seagate (model: ST16000NM00J) drive model had zero failures. With only 185 drives in service, there is a lot of potential variability in the future, but for the moment, they are settling in quite well.
  • The nine year club. There are no data drives with 10 or more years of service, but there are 39 drives that are nine years or older. They are all 4TB HGST drives (model: HMS5C4040ALE640) spread across 31 different Storage Pods, in five different Backblaze Vaults and two different data centers. Will any of those drives make it to 10 years? Probably not, given that four of the five vaults have started their CVT migrations and will be gone by the end of the year. And, while the fifth vault is not scheduled for migration yet, it is just a matter of time before all of the 4TB drives we are using will be gone.

Reactive and proactive drive failures

In the Drive Stats dataset schema, there is a field named failure, which displays either a 1 for failure or a 0 for not failed. Over the years in various posts, we have stated that for our purposes drive failure is either reactive or proactive. Furthermore, we have suggested that failed drives fall basically evenly into these two categories. We’d like to put some data behind that 50/50 number, but first let’s start by defining our two categories of drive failure, reactive and proactive. 

  • Reactive: A reactive failure is when any of the following conditions occur: the drive crashes and refuses to boot or spin up, the drive won’t respond to system commands, or the drive won’t stay operational. 
  • Proactive: A proactive failure is generally anything not a reactive failure, and typically is when one or more indicators such as SMART stats, FSCK (file system) checks, etc., signal that the drive is having difficulty and drive failure is highly probable. Typically a multitude of indicators are present in drives declared as proactive failures.

A drive that is removed and replaced as either a proactive or reactive failure is considered a drive failure in Drive Stats unless we learn otherwise. For example, a drive is experiencing communications errors and command timeouts and is scheduled for a proactive drive replacement. During the replacement process, the data center tech realizes the drive does not appear to be fully seated. After gently securing the drive, further testing reveals no issues and the drive is no longer considered failed.  At that point, the Drive Stats dataset is updated accordingly.

As noted above, the Drive Stats dataset includes the failure status (0 or 1) but not the type of failure (proactive or reactive). That’s a project for the future. To get a breakdown of different types of drives failure we have to interrogate the data center maintenance ticketing system used by each data center to record any maintenance activities on Storage Pods and related equipment. Historically, the drive failure data was not readily accessible, but a recent software upgrade now allows us access to this data for the first time. So in the spirit of Drive Stats, we’d like to share our drive failure types with you. 

Drive failure type stats

Q3 2024 will be our starting point for any drive failure type stats we publish going forward. For consistency, we will use the same drive models listed in the Drive Stats quarterly report, in this case Q3 2024. For this period, there were 1,361 drive failures across 29 drive models. 

We actually have been using the data center maintenance data for several years as each quarter we validate the failed drives reported by the Drive Stats system with the maintenance records. Only validated failed drives are used for the Drive Stats reports we publish quarterly and in the data we publish on our Drive Stats webpage.

The recent upgrades to the data center maintenance ticketing system have not only made the drive failure validation process easier, we can now easily join together the two sources. This gives us the ability to look at the drive failure data across several different attributes as shown in the tables below. We’ll start with the number of failed drives in each category and go from there. This will form our baseline data.

Reactive vs. proactive drive failures for Q3 2024

Observation period Reactive failures Proactive failures Total failures Reactive % Proactive%
Q3 2024 failed drives 640 721 1,361 47.0% 53.0%

Reactive vs. proactive drive failures for Q3 2024

Manufacturer Reactive failures Proactive failures Total failures Reactive % Proactive %
HGST 194 177 371 52.3% 47.7%
Seagate 258 272 530 48.7% 51.3%
Toshiba 124 221 345 35.9% 64.1%
WDC 64 51 115 55.7% 44.3%

Reactive vs. proactive drive failures by Backblaze data center

Backblaze data center Reactive failures Proactive failures Total failures Reactive % Proactive %
AMS 36 77 113 31.9% 68.1%
IAD 50 92 142 35.2% 64.8%
PHX 179 201 380 47.1% 52.9%
SAC 0 151 148 299 50.5% 49.5%
SAC 2 224 203 427 52.5% 47.5%

Reactive vs. proactive drive failures by server type

Server type Reactive failures Proactive failures Total failures Reactive % Proactive %
5.0 red Storage Pod (45 drives) 4 2 6 66.7% 33.3%
6.0 red Storage Pod (60 drives) 433 349 782 55.4% 44.6%
6.1 red Storage Pod (60 drives) 70 107 177 39.5% 60.5%
Dell Server (26 drives) 22 61 83 26.5% 73.5%
Supermicro Server (60 drives) 111 202 313 35.5% 64.5%

Obviously, there are many things we could analyze here, but for the moment we just want to establish a baseline. Next, we’ll collect additional data to see how consistent and reliable our data is over time. We’ll let you know what we find.

Learning more about proactive failures

One item of interest to us is the different reasons that cause a drive to be designated as a proactive failure. Today we record the reasons for the proactive designation at the time the drive is flagged for replacement, but currently multiple reasons are allowed for a given drive. This makes determining the primary reason difficult to determine. Of course, there may be no such thing as a primary reason, as it is often a combination of factors causing the problem. That analysis could be interesting as well. Regardless of the exact reason, such drives are in bad shape and replacing degraded drives to protect the data they store is our first priority.

Lifetime hard drive failure rates

As of the end of Q3 2024, we were tracking 288,547 operational hard drives. To be considered for the lifetime review, a drive model was required to have 500 or more drives as of the end of Q3 2024 and have over 100,000 accumulated drive days during their lifetime. When we removed those drive models which did not meet the lifetime criteria, we had 286,892 drives grouped into 25 models remaining for analysis as shown in the table below.

Downward lifetime AFR

In Q2 2024, the lifetime AFR for the drives listed was 1.47%. In Q3, the lifetime AFR went down to 1.31%, a significant decrease from one quarter to the next for the lifetime AFR. This decrease is also contrary to the increasing quarterly AFR increase over the same period. At first blush, that doesn’t make much sense as an increasing quarter-to-quarter AFR should increase the lifetime AFR. There are two related factors which explain this seemingly contradictory data. Let’s take a look. 

We’ll start with the table below which summarizes the differences between the Q2 and Q3 lifetime stats.

Period Drive count Drive days Drive failures Lifetime AFR
Q2 2024 283,065 469,219,469 18,949 1.47%
Q3 2024 286,892 398,476,931 14,308 1.31%

To create the dataset for the lifetime AFR tables two criteria are applied: first, at the end of a given quarter, the number of drives of a drive model must be greater than 500, and, second, the number of drive days must be greater than 100,000. The first  criterion ensures that the drive models are relevant to the data presented; that is, we have a significant number of each of the included drive models. The second standard ensures that the drive models listed in the lifetime AFR table have a sufficient number of data points; that is, they have enough drive days to be significant. 

As we can see in the table above, while the number of drives went up from Q2 to Q3, the number of drive days and the number of drive failures went down significantly. This is explained by comparing the drive models listed in the Q2 lifetime table versus the Q3 lifetime table. Let’s summarize.

  • Added: In Q3, we added the 20TB Toshiba drive model (MG10ACA20TE). In Q2, there were only two of these drives in service.
  • Removed: In Q3, we removed the 4TB Seagate drive model (ST4000DM000) as there were only two drives remaining as of the end of Q3, well below the criteria of 500 drives.

When we removed the 4TB Seagate drives we also removed 80,400,065 lifetime drive days and 5,789 lifetime drive failures from the Q3 lifetime AFR computations. If the 4TB Seagate drive model data (drive days and drive failures) was included in the Q3 Lifetime stats, the AFR would have been 1.50%. 

Why not include the 4TB Seagate data? In other words, why have a drive count criteria at all? Shouldn’t we compute lifetime AFR using all of the drive models we have ever used which accumulated over 100,000 drive days in a lifetime? If we did things that way, the list of drive models used to compute the lifetime AFR would now include drive models we stopped using years ago and would include nearly 100 different drive models. As a result, a majority of the drive models used to compute the lifetime AFR would be outdated and the lifetime AFR table would contain rows of basically useless data that has no current or future value. In short, having drive count as one of the criteria in computing lifetime AFR keeps the table relevant and approachable.

The Hard Drive Stats data

It has now been over 11 years since we began recording, storing, and reporting the operational statistics of the HDDs and SSDs we use to store data at Backblaze. We look at the telemetry data of the drives, including their SMART stats and other health related attributes. We do not read or otherwise examine the actual customer data stored. 

Over the years, we have analyzed the data we have gathered and published our findings and insights from our analyses. For transparency, we also publish the data itself, known as the Drive Stats dataset. This dataset is open source and can be downloaded from our Drive Stats webpage.

You can download and use the Drive Stats dataset for free for your own purpose. All we ask are three things: 1) you cite Backblaze as the source if you use the data, 2) you accept that you are solely responsible for how you use the data, 3) you may sell derivative works based on the data, but 4) you can not sell this data to anyone; it is free.

Good luck, and let us know if you find anything interesting.

The post Backblaze Drive Stats for Q3 2024 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

AWS BuilderCards second edition at re:Invent 2024

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/aws-buildercards-second-edition-available-at-reinvent-2024-and-online/

I have been following the progress of AWS BuilderCards for several years. Players of all skill levels use the cards to learn about AWS in a fun and engaging way, competing (in a friendly fashion) to combine their cards to form architectures, gaining knowledge and scoring points as they play:

To date, more than 15,000 sets of BuilderCards have been printed and put to use over the course of three re:Invents, fifteen AWS Summits, and multiple community events. For example, here is a group of AWS enthusiasts having a good time in Tokyo during JAWS Days 2024:

Feedback from players has been incredibly positive, with a 4.8 star customer satisfaction score (CSAT) across more than 1500 replies.

Second Edition Now Available
I am happy to announce that the second edition of AWS BuilderCards will be distributed at re:Invent 2024 and will soon be available for purchase online. In response to feedback on the first edition, we have made many changes to the second edition. Here’s a summary:

Design — The revised design focuses on the contents of the card, with additional gradients and patterns to make the cards more attractive and playful. The font size was increased, game effects are now represented as icons, and the QR codes now point to the BuilderCards site:

Game Mechanics — The mechanics have been revised to improve balance, simplify play, and remove some bias. There are also some starter cards that represent a common on-premises data center environment.

Generative AI Add-On Pack — This new deck includes 50 additional BuilderCards designed to show how Generative AI and AWS architecture align. This add-on pack also includes a set of Mission cards. These cards add context, with QR codes that link to published best practices or solutions. The cards are larger, with additional text and an architecture diagram. Use is optional, with players earning extra points for completing a mission. Each deck also includes five blank BuilderCards and two blank Mission cards to support customization:

Get Your BuilderCards
If you will be at re:Invent 2024, make plans to visit the BuilderCards play area on Level 1 of Caesar’s Forum next to the PeerTalk area:

Sunday – 10 AM to 6 PM
Monday – 9 AM to 5 PM
Tuesday – 9 AM to 5 PM
Wednesday – 9 AM to 5 PM
Thursday – 9 AM to 4 PM

You can play against other re:Invent attendees and also get your own game and add-on packs to take home (we’ll give away 1,000 per day). Thanks to hard work by Masanori Yamaguchi (AWS Hero) and Kosuke Enomoto (AWS Community Builder) we will also have BuilderCards in Japanese for on-site play. You can read Kosuke’s blog post (AWS BuilderCards Japanese Edition for JAWS DAYS) to learn more about the translation process.

If you won’t be able to attend re:Invent, you will soon be able to purchase a deck of your own. Check back here for more info!

Stay Tuned
The BuilderCards team is working on additional goodies including expansion packs and additional language packs.

Jeff;

Fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock is now generally available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/fine-tuning-for-anthropics-claude-3-haiku-model-in-amazon-bedrock-is-now-generally-available/

Today, we are announcing the general availability of fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock in the US West (Oregon) AWS Region. Amazon Bedrock is the only fully managed service that provides you with the ability to fine-tune Claude models. You can now fine-tune and customize the Claude 3 Haiku model with your own task-specific training dataset to boost model accuracy, quality, and consistency to further tailor generative AI for your business.

Fine-tuning is a technique where a pre-trained large language model (LLM) is customized for a specific task by updating the weights and tuning hyperparameters like learning rate and batch size for optimal results.

Anthropic’s Claude 3 Haiku model is the fastest and most compact model in the Claude 3 model family. Fine-tuning Claude 3 Haiku offers significant advantages for businesses:

  • Customization – You can customize models that excel in areas crucial to your business compared to more general models by encoding company and domain knowledge.
  • Specialized performance – You can generate higher quality results and create unique user experiences that reflect your company’s proprietary information, brand, products, and more.
  • Task-specific optimization – You can enhance performance for domain-specific actions such as classification, interactions with custom APIs, or industry-specific data interpretation.
  • Data security – You can fine-tune with peace of mind in your secure AWS environment. Amazon Bedrock makes a separate copy of the base foundation model that is accessible only by you and trains this private copy of the model.

You can now optimize performance for specific business use cases by providing domain-specific labeled data to fine-tune the Claude 3 Haiku model in Amazon Bedrock.

In early 2024, we started to engage customers with a team of experts from the AWS Generative AI Innovation Center to help fine-tune Anthropic’s Claude models with their proprietary data sources. I’m happy to share that you can now fine-tune Anthropic’s Claude 3 Haiku model in Amazon Bedrock directly in the Amazon Bedrock console.

Get started with fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock
I will demonstrate how to easily fine-tune the Claude 3 Haiku model in Amazon Bedrock. To learn more about the fine-tuning workflow in detail, visit the AWS Machine Learning Blog post, Fine-tune Anthropic’s Claude 3 Haiku in Amazon Bedrock to boost model accuracy and quality.

To create a simple fine-tuning job in the Amazon Bedrock console, go to the Foundation models section in the navigation pane and select Custom models. In the Models section, select the Customize model button and then select Create Fine-tuning job.

Next, choose the model that you want to customize with your own data, give your resulting model a name, and optionally add encryption keys and any tags to associate with the model in the Model details section. Enter a name for the job and optionally add any tags for the job in the Job configuration section.

You can select the Amazon S3 location of the training dataset file and, if applicable, the validation dataset file in the Input data section.

Each dataset can be created using a JSON Lines (JSONL) file with multiple JSON lines using the single-turn or multi-turn messaging format. Each JSON line is a sample containing a system and message, an array of message objects.

I prepared some of the latest information about Anthropic’s Claude 3.5 Sonnet model in Amazon Bedrock. To learn more, visit Prepare the datasets in the Amazon Bedrock documentation.

{"system": "You are an helpful assistant.","messages":[{"role": "user", "content": "What’s the latest models to support Amazon Bedrock"},{"role": "assistant", "content": "Amazon Bedrock is a fully managed service that support Anthropic’s Claude 3 Sonnet, Haiku, and Opus models and the latest Claud 3.5 Sonnet model."}]}
{"system": "You are an helpful assistant.","messages":[{"role": "user", "content": "How long context window of Claude 3.5?"},{"role": "assistant", "content": "Anthropic's Claude 3 models have a 200,000 token context window enabling you to relay a large volume of information to Claude. This translates to roughly 150,000 words, or over 500 pages of material."}]}
{"system": "You are an helpful assistant.","messages":[{"role": "user", "content": "Is Claude 3.5 available in Bedrock?"},{"role": "assistant", "content": "Anthropic’s most intelligent and advanced model, Claude 3.5 Sonnet, demonstrates exceptional capabilities across a diverse range of tasks and evaluations while also outperforming Claude 3 Opus."}]}

In the Hyperparameters section, enter values for hyperparameters to use in training, such as epochs, batch size, and learning rate multiplier. If you’ve included a validation dataset, you can enable Early stopping, a technique used to prevent overfitting and stop the training process when the validation loss stops improving. You can set an early stopping threshold and patience value.

You can also select the output location where Amazon Bedrock should save the output of the job in the Output data section. Choose an AWS Identity and Access Management (IAM) custom service role with the appropriate permissions in the Service access section. To learn more, see Create a service role for model customization in the Amazon Bedrock documentation.

Finally, choose Create Fine-tuning job and wait for your fine-tuning job to start.

You can track its progress or stop it in the Jobs tab in the Custom models section.

After a model customization job is complete, you can analyze the results of the training process by looking at the files in the output Amazon Simple Storage Service (Amazon S3) folder that you specified when you submitted the job, or you can view details about the model.

Before using a customized model, you need to purchase Provisioned Throughput for Amazon Bedrock and then use the resulting provisioned model for inference. When you purchase Provisioned Throughput, you can select a commitment term, choose a number of model units, and see estimated hourly, daily, and monthly costs. To learn more about the custom model pricing for the Claude 3 Haiku model, visit Amazon Bedrock Pricing.

Now, you can test your custom model in the console playground. I choose my custom model and ask whether Anthropic’s Claude 3.5 Sonnet model is available in Amazon Bedrock.

I receive the answer:

Yes. You can use Anthropic’s most intelligent and advanced model, Claude 3.5 Sonnet in the Amazon Bedrock. You can demonstrate exceptional capabilities across a diverse range of tasks and evaluations while also outperforming Claude 3 Opus.

You can complete this job using AWS APIs, AWS SDKs, or AWS Command Line Interface (AWS CLI). To learn more about using AWS CLI, visit Code samples for model customization in the AWS documentation.

If you are using Jupyter Notebook, visit the GitHub repository and follow a hands-on guide for custom models. To build a production-level operation, I recommend reading Streamline custom model creation and deployment for Amazon Bedrock with Provisioned Throughput using Terraform on the AWS Machine Learning Blog.

Datasets and parameters
When fine-tuning Claude 3 Haiku, the first thing you should do is look at your datasets. There are two datasets that are involved in training Haiku, and that’s the Training dataset and the Validation dataset. There are specific parameters that you must follow in order to make your training successful, which are outlined in the following table.

Training data Validation data
File format JSONL
File size <= 10GB <= 1GB
Line count 32 – 10,000 lines 32 – 1,000 lines
Training + Validation Sum <= 10,000 lines
Token limit < 32,000 tokens per entry
Reserved keywords Avoid having “\nHuman:” or “\nAssistant:” in prompts

When you prepare the datasets, start with a small high-quality dataset and iterate based on tuning results. You can consider using larger models from Anthropic like Claude 3 Opus or Claude 3.5 Sonnet to help refine and improve your training data. You can also use them to generate training data for fine-tuning the Claude 3 Haiku model, which can be very effective if the larger models already perform well on your target task.

For more guidance on selecting the proper hyperparameters and preparing the datasets, read the AWS Machine Learning Blog post, Best practices and lessons for fine-tuning Anthropic’s Claude 3 Haiku in Amazon Bedrock.

Demo video
Check out this deep dive demo video for a step-by-step walkthrough that will help you get started with fine-tuning Anthropic’s Claude 3 Haiku model in Amazon Bedrock.

Now available
Fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock is now generally available in the US West (Oregon) AWS Region; check the full Region list for future updates. To learn more, visit Custom models in the Amazon Bedrock documentation.

Give fine-tuning for the Claude 3 Haiku model a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

I look forward to seeing what you build when you put this new technology to work for your business.

Channy

Unlock the potential of your supply chain data and gain actionable insights with AWS Supply Chain Analytics

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/unlock-the-potential-of-your-supply-chain-data-and-gain-actionable-insights-with-aws-supply-chain-analytics/

Today, we’re announcing the general availability of AWS Supply Chain Analytics powered by Amazon QuickSight. This new feature helps you to build custom report dashboards using your data in AWS Supply Chain. With this feature, your business analysts or supply chain managers can perform custom analyses, visualize data, and gain actionable insights for your supply chain management operations.

Here’s how it looks:

AWS Supply Chain Analytics leverages the AWS Supply Chain data lake and provides Amazon QuickSight embedded authoring tools directly into the AWS Supply Chain user interface. This integration provides you with a unified and configurable experience for creating custom insights, metrics, and key performance indicators (KPIs) for your operational analytics.

In addition, AWS Supply Chain Analytics provides prebuilt dashboards that you can use as-is or modify based on your needs. At launch, you will have the following prebuilt dashboards:

  1. Plan-Over-Plan Variance: Presents a comparison between two demand plans, showcasing variances in both units and values across key dimensions such as product, site, and time periods.
  2. Seasonality Analytics: Presents a year-over-year view of demand, illustrating trends in average demand quantities and highlighting seasonality patterns through heatmaps at both monthly and weekly levels.

Let’s get started
Let me walk you through the features of AWS Supply Chain Analytics.

The first step is to enable AWS Supply Chain Analytics. To do this, navigate to Settings, then select Organizations and choose Analytics. Here, I can Enable data access for Analytics.

Now I can edit existing roles or create a new role with analytics access. To learn more, visit User permission roles.

Once this feature is enabled, when I log in to AWS Supply Chain I can access the AWS Supply Chain Analytics feature by selecting either the Connecting to Analytics card or Analytics on the left navigation menu.

Here, I have an embedded Amazon QuickSight interface ready for me to use. To get started, I navigate to Prebuilt Dashboards.

Then, I can select the prebuilt dashboards I need in the Supply Chain Function dropdown list:

What I like the most about this prebuilt dashboards is I can easily get started. AWS Supply Chain Analytics will prepare all the datasets, analysis, and even a dashboard for me. I select Add to begin.

Then, I navigate to the dashboard page, and I can see the results. I can also share this dashboard with my team, which improves the collaboration aspect.

If I need to include other datasets for me to build a custom dashboard, I can navigate to Datasets and select New dataset.

Here, I have AWS Supply Chain data lake as an existing dataset for me to use.

Next, I need to select Create dataset.

Then, I can select a table that I need to include into my analysis. On the Data section, I can see all available fields. All data sets that start with asc_ are generated by AWS Supply Chain, such as data from Demand Planning, Insights, Supply Planning, and others.

I can also find all the datasets I have ingested into AWS Supply Chain. To learn more on data entities, visit the AWS Supply Chain documentation page. One thing to note here is if I have not ingested data into AWS Supply Chain Data Lake, I need to ingest data before using AWS Supply Chain Analytics. To learn how to ingest data into the data lake, visit the data lake page.

At this stage, I can start my analysis. 

Now available
AWS Supply Chain Analytics is now generally available in all regions where AWS Supply Chain is offered. Give it a try to experience and transform your operations with the AWS Supply Chain Analytics.

Happy building,
— Donnie

Quoth the Drive Stats, Nevermore: An Elegy for Our Seagate 4TB Drives

Post Syndicated from Andy Klein original https://www.backblaze.com/blog/quoth-the-drive-stats-nevermore-an-elegy-for-our-seagate-4tb-drives/

A decorative image showing a gravestone with ravens around it.

Once upon a midnight dreary, as I typed another query

Seeking many a quaint and curious fact of hidden Drive Stats lore—

While I waited, time advancing, suddenly the stats came dancing

Lines of empty datasets; the database had nothing more

“Is that right?” I muttered, “The database had nothing more—

So those drives, I must explore.”

Ah, distinctly I remember, it was just past this September

I requested failure rates of Seagate drives with terabytes of four

Eagerly I typed the query, even though my eyes were bleary

The count of Seagate fours was eerie, eerie; there was nothing more.

The sad and certain count screamed like it never had before;

No Seagate drives with terabytes of four.

There are missing rows, I’m certain, and files waiting to explore.

The reality I kept dismissing, the Seagate data must be missing

With hours gone to data fishing, the facts shook me to the core;

The spinning life is over for our Seagate drives with terabytes of four—

Those Seagate drives are nevermore.

(My apologies to Edgar Allen Poe.)

Shortly, we will publish the Q3 2024 Backblaze Drive Stats report, and an old faithful will be missing from the tables, the 4TB Seagate drive model ST4000DM000. This drive model has graced our Drive Stats charts and tables since the very first Drive Stats report, and it would be a ghastly mistake if we let the drive slip into the afterlife unnoticed. So on this All Hallows’ Eve, it’s only fitting we say nevermore to these Seagate drives.

The first 45 of these Seagate 4TB drives were installed in a 45-drive Backblaze Storage Pod in May 2013. That was before 60-drive Storage Pods, Backblaze Vaults, and even Backblaze B2. Over the next two years, thousands of new Seagate 4TB drives were added each quarter, and by Q3 2016, there were 34,744 spinning souls in service. That represented more than 50% of all the drives in service at the time—a howling success that has not been duplicated by any other drive model.

Alas, that didn’t last as the first wave of 8TB drives arrived in mid-2016 and with that, no additional 4TB Seagate drives were procured. Over time, as 4TB Seagate drives met their maker, the count decreased, and when Storage Pods containing these drives started being phased out in 2018, the count dropped faster. The final nail in the coffin came when, in 2023, our CVT drive migration system became fixated on the replacement of all the remaining 4TB Seagate drives, and here we are.

As for those intrepid 45 original drives installed in May 2013, they were not around at the end. They were unceremoniously replaced in a Storage Pod upgrade back in 2017. A few were resurrected as drive replacements, but today they only exist in the spirit world, having died or been replaced by 2020. Still many other 4TB Seagate drives have lived long happy lives, with nearly 100 exceeding 100 months of service (8.4 years) before being sent to their final resting place by the CVT reaper.

And so it is time; we shall gather in a circle, cross our arms and hold hands and chant “our Seagate drives…with terabytes of four…are nevermore!”

The post Quoth the Drive Stats, Nevermore: An Elegy for Our Seagate 4TB Drives appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Backblaze Partners with Opti9 and Adds Canadian Data Region

Post Syndicated from Teresa Dodson original https://www.backblaze.com/blog/backblaze-partners-with-opti9-and-adds-canadian-data-region/

A decorative image showing the Backblaze and Opti9 logos.

Backblaze and Opti9 are partnering up to bring Backblaze B2 Cloud Storage to joint customers around the world as well as businesses in Canada who are required to keep their data within national borders.

The who and the why

Opti9 is the international leader in hybrid cloud solutions that delivers managed cloud services, application development and modernization, backup and disaster recovery, security, and compliance solutions to businesses around the world. By bringing Backblaze into their solution set, Opti9 is onboarding high performance, low cost cloud storage that works within all the solutions they provide.

Increasingly, companies seeking managed services support are demanding solutions made up of best-in-breed providers. While traditional cloud platforms work against this principle of interoperability, Backblaze and solution providers like Opti9 are committed to delivering cloud solutions without the limitations, complexity, and high pricing that are holding businesses back.

As Jim Stechyson, the President of Opti9 put it:

Backblaze and Opti9 focus on empowering businesses with the best cloud solutions available. Being able to integrate the high performance and low total cost of ownership of Backblaze’s object storage into our set of solutions will greatly enhance our ability to drive success for our customers.

How to get started

Interested resellers or customers who want to start working with Opti9 and Backblaze today can go to the Opti9 website. Check out our joint S3 compatible hot storage offering and book your demo to get started.

Book a Demo ➔ 

For customers based in Canada, Backblaze will be opening a new data region centered in Toronto in the first quarter of 2025. As part of the partnership, Opti9 will be the exclusive provider of server backup solutions in the Canadian channel for Backblaze B2 Reserve and the Powered by Backblaze program.

More about the new Backblaze data region in Canada

The new Canadian data region gives businesses the freedom to access Backblaze’s open, interoperable cloud solution, while still allowing customers to benefit from local storage and compliance. Located in Toronto, Ontario, the data center has been assessed and maintains a security program that addresses the requirements of SOC 1 Type 2, SOC 2 Type 2, ISO 27001, PCI DSS, and HIPAA. The region will be available to customers in the first quarter of 2025. 

If you’d like to receive notifications about the data region opening date and when you can start storing data in Canada, you can sign up for the waitlist today.

Notify Me ➔ 

The post Backblaze Partners with Opti9 and Adds Canadian Data Region appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

SaaS and the Shared Responsibility Model: A Guide to Protecting Your Data

Post Syndicated from Vinodh Subramanian original https://www.backblaze.com/blog/saas-and-the-shared-responsibility-model-a-guide-to-protecting-your-data/

A decorative image showing a Venn diagram with a cloud overtop it.

Were you the person who stayed up until 2 a.m. to finish the group project? If you, like me, burned the midnight oil to save the team from utter failure, you suffered from a breakdown of shared responsibility. No one knew who was supposed to do what.

The same breakdown applies when you don’t fully understand the “shared responsibility model” that most software as a service (SaaS) platforms use when it comes to your data. You might assume that, because it’s in the cloud, your SaaS data is protected automatically. In reality, SaaS companies are only responsible for maintaining their uptime, not for retaining your files and critical information in case you need to get back online—and this has big implications for how you protect your data, ensure compliance, and optimize system performance.

Today, I’m diving into what this model means and how it affects how you use SaaS platforms.

What is the shared responsibility model?

The shared responsibility model defines the division of duties between a SaaS provider and its customers. It delineates which aspects of the system the provider manages and what tasks remain under the customer’s control. The primary goal is to clarify roles and reduce any ambiguity about who is responsible for certain aspects of security, data integrity, and system maintenance. 

Defined roles, reduced ambiguity. That all sounds great to me, but what do SaaS providers actually take responsibility for? And what are you responsible for? 

SaaS provider responsibilities

First and foremost, SaaS providers are responsible for ensuring that the application and its underlying infrastructure (servers, networking, data centers) are secure. This includes physical security, network protection, patching the platform, and overall system integrity. They typically guarantee a certain level of service availability, often formalized in a service level agreement (SLA). Downtime, system performance, and platform updates fall within the vendor’s scope.

Practically speaking, that means that they may not back up your data as often as you would like or archive it for as long as you need. SaaS vendors do not concern themselves with fully protecting your files. Most importantly, they may not offer a timely recovery option if you lose the data, which is critical to getting your business back online in the event of an outage. 

Customer responsibilities

SaaS providers and cloud drives typically take responsibility for the security “of” the cloud, including the infrastructure that runs all of the services offered in the cloud. On the other hand, the customers are responsible for security “in” the cloud. This means customers must manage the security of their own data.

What’s the difference? Let’s use an example I’ve come across many times. If a user inadvertently uploads a ransomware-infected file to a cloud drive like Google Drive or OneDrive, the service might protect the integrity of the cloud infrastructure, ensuring the malware doesn’t spread to other users. However, the responsibility to prevent the upload of the infected file in the first place, and managing its consequences, falls directly on the user. In essence, while cloud drives provide a platform for storing your data, relying solely on them without understanding the nuances of the shared responsibility model could leave gaps in your data protection strategy. 

Customer responsibilities include, among others:

  • Data protection: While the provider secures the infrastructure, you are responsible for securing the data you upload, manage, and store within the platform. SaaS platforms may replicate data and have redundancy safeguards in place to ensure you can access your data through the platform reliably, but they do not assume responsibility for their users’ data. It’s up to you to ensure your data is backed up according to your needs and policies.
  • Access management: You are responsible for controlling who has access to the SaaS environment. This involves creating strong user authentication processes, managing roles and permissions, and ensuring that the right people have access to the right information.
  • Compliance: Even if the SaaS vendor is compliant with say HIPAA or GDPR standards, you are also responsible for ensuring that you’re using the platform in accordance with those standards.

Here’s a graph that shows how shared responsibility breaks down for Microsoft 365 as just one example:

A diagram of the shared responsibility model.

When the shared responsibility model matters

Unfortunately, I’ve found the shared responsibility model can create a false sense of security because understanding your responsibilities as a customer is often a process of elimination. SaaS responsibilities may be hard to track down, and when you can find them, they won’t say “you need to handle backups.” They’ll list what the provider handles, and all the rest is up to you.  

When does this become important for you?

  • Security breaches: Many security incidents occur because of a misunderstanding of this model. For example, if a company assumes their SaaS provider is responsible for data encryption and user access control when, in fact, the company is, this can lead to critical vulnerabilities. A lack of clarity can expose businesses to data breaches, financial losses, and reputational damage.
  • Compliance issues: Regulatory compliance is another area that hinges on understanding shared responsibilities. Organizations that fail to implement required security measures or back up data properly can face fines, penalties, or legal consequences—even if the SaaS provider adheres to all necessary certifications.
  • Operational efficiency: Knowing where your responsibility starts and ends helps optimize how you use the platform. You can improve operational efficiency by focusing on the areas you control.

And, this gets even more complicated the larger your business and the more complicated your processes. So, if you have a business running on Google Workspace or M365, you can take something like emails and understand that Google is responsible for the email platform, but you should backup the individual emails themselves. But what about when you’re a media management company using best-of-breed tools for editing and collaboration, transcoding, asset management, and maybe even content delivery? All of those platforms have some responsibility in a shared responsibility model, and your job as a business is to understand where you are vulnerable—and then plug the gaps.

Navigating the shared responsibility model

So, what should you do with all of this information? In my experience, these are the biggest takeaways businesses can put into practice to successfully navigate the shared responsibility model:

  1. Know your provider’s SLAs and security measures. Before adopting a SaaS solution, ensure you have a clear understanding of the vendor’s SLA and their security protocols. Understand the terms of their compliance with data privacy regulations, system availability, and disaster recovery.

What are Backblaze’s security and compliance protocols?

…is a question that would absolutely make sense for you to be asking. And I’m glad you did. Check out our Security and Compliance pages to learn more.

  1. Educate your teams. Make sure that your internal teams are aware of their responsibilities in the shared model. Provide training on access control, data management, and security best practices to prevent accidental data exposure or misconfigurations.
  2. Monitor and audit your usage. Set up regular audits to ensure that your organization is meeting its obligations under the shared responsibility model. Use tools to monitor access, detect unusual activity, and ensure data is being properly managed.
  3. Make sure your backups are comprehensive. If you’re here, you’re probably well aware of this, but I can’t stress enough how important it is to back up your data, including data stored in cloud services like Microsoft 365, Google Drive, and OneDrive. Even if these services offer backups as part of the service, they may not meet your recovery needs.

How to approach the shared responsibility model

All this to say, you are ultimately responsible for backing up your data and files stored in SaaS clouds or cloud drives. The bottom line is that SaaS platforms’ top priority is to keep their own services running. By clearly understanding your role and responsibilities in this model, you can not only protect your data and ensure compliance, but also maximize the value of your SaaS investments.

The post SaaS and the Shared Responsibility Model: A Guide to Protecting Your Data appeared first on Backblaze Blog | Cloud Storage & Cloud Backup