Tag Archives: monitoring

Building HA Zabbix with PostgreSQL and Patroni

Post Syndicated from Patrik Uytterhoeven original https://blog.zabbix.com/building-ha-zabbix-with-postgresql-and-patroni/30960/

Running a monitoring platform like Zabbix in a production environment demands reliability and resilience. When your monitoring solution is down, you’re flying blind – and for many organizations, that simply isn’t acceptable. This post introduces a robust high-availability (HA) architecture for Zabbix, using PostgreSQL,  Patroni, etcd, HAProxy, keepalived and PgBackRest. Built on RHEL 9 or derrivates, this solution combines modern open-source tools to provide automatic failover, load balancing, and seamless monitoring, all while maintaining consistency and performance.

Architecture overview

The HA design consists of multiple layers working in tandem to maintain continuity even during node or service failures:

Database Cluster Layer

2 or more nodes form the PostgreSQL cluster, managed by Patroni and coordinated using etcd. At any given time, one node is the primary (read/write), and the others are hot standbys ready to take over automatically.

Consensus layer

etcd runs on the same nodes and acts as the distributed configuration store and coordination layer for Patroni. It ensures a consistent cluster state and enables safe failover decisions.

Load balancing layer  

Two HAProxy nodes provide a single point of entry for all clients (including Zabbix), routing requests to the current PostgreSQL primary. These nodes are monitored and coordinated via Keepalived to maintain a floating Virtual IP (VIP), ensuring seamless failover at the connection layer.

Backup layer

A separate backup server is responsible for running PgBackRest, which handles full and incremental backups, WAL archiving, and Point-In-Time Recovery (PITR). This server communicates securely with all database nodes over SSH.

Monitoring layer

Two Zabbix servers, running in active-passive mode, continuously monitor all layers of this stack including the HAProxy health, Patroni cluster role, and etcd status by accessing the PostgreSQL VIP for backend connectivity.

This multi-tiered setup ensures that no single failure be it a database, load balancer, or monitoring server brings down the monitoring platform.

Why HA matters for Zabbix

Zabbix depends heavily on its PostgreSQL database backend. Every metric, trigger, event, and alert is stored there. If PostgreSQL becomes unavailable, even briefly, data loss or monitoring blind spots can occur. That’s why introducing HA at the database layer is a crucial step when scaling Zabbix for enterprise environments.

While Zabbix itself supports HA at the application level, this architecture ensures that the database backend is also fully fault-tolerant, using modern consensus-based clustering with automatic failover.

Component overview

To achieve HA, we bring together several specialized components, each fulfilling a critical role in the system:

PostgreSQL

The relational database engine used by Zabbix. In this example setup, it runs on three nodes, forming a cluster managed by Patroni.

Patroni

Patroni is the orchestrator for the PostgreSQL cluster. It monitors node health, manages replication, promotes standbys when needed, and ensures only one writable leader exists at any time. Patroni leverages a distributed consensus store in this case, etcd but other DCS’s are possible to coordinate decisions across the cluster.

etcd

etcd is a lightweight and highly available key-value store used by Patroni to maintain the cluster’s state. It stores leader election data, health statuses, and locks. We deploy it as a three-node cluster, co-located with the PostgreSQL nodes for convenience, though this setup can be scaled independently if needed as etcd is very latency prone.

HAProxy

To simplify application connectivity, HAProxy acts as a load balancer in front of the database cluster. It monitors the role of each node using Patroni’s REST API and routes connections to the active primary server. If the leader fails, HAProxy automatically reroutes traffic to the new primary.
Keepalived

Keepalived provides a floating virtual IP address (VIP) across the HAProxy nodes. This VIP allows client systems, such as the Zabbix frontend, to connect to a single stable IP even if one HAProxy node fails.

PgBackRest

To protect the data itself, we use PgBackRest for full and incremental backups, as well as Point-In-Time Recovery (PITR). A dedicated backup server is included to pull and store archive logs and backups securely via SSH.

Zabbix server

Finally, we run two Zabbix servers in active-passive mode. Both are configured to connect to the PostgreSQL cluster through the VIP exposed by HAProxy. The Zabbix frontend is deployed on both nodes as well, ensuring continued accessibility through the load-balanced setup.

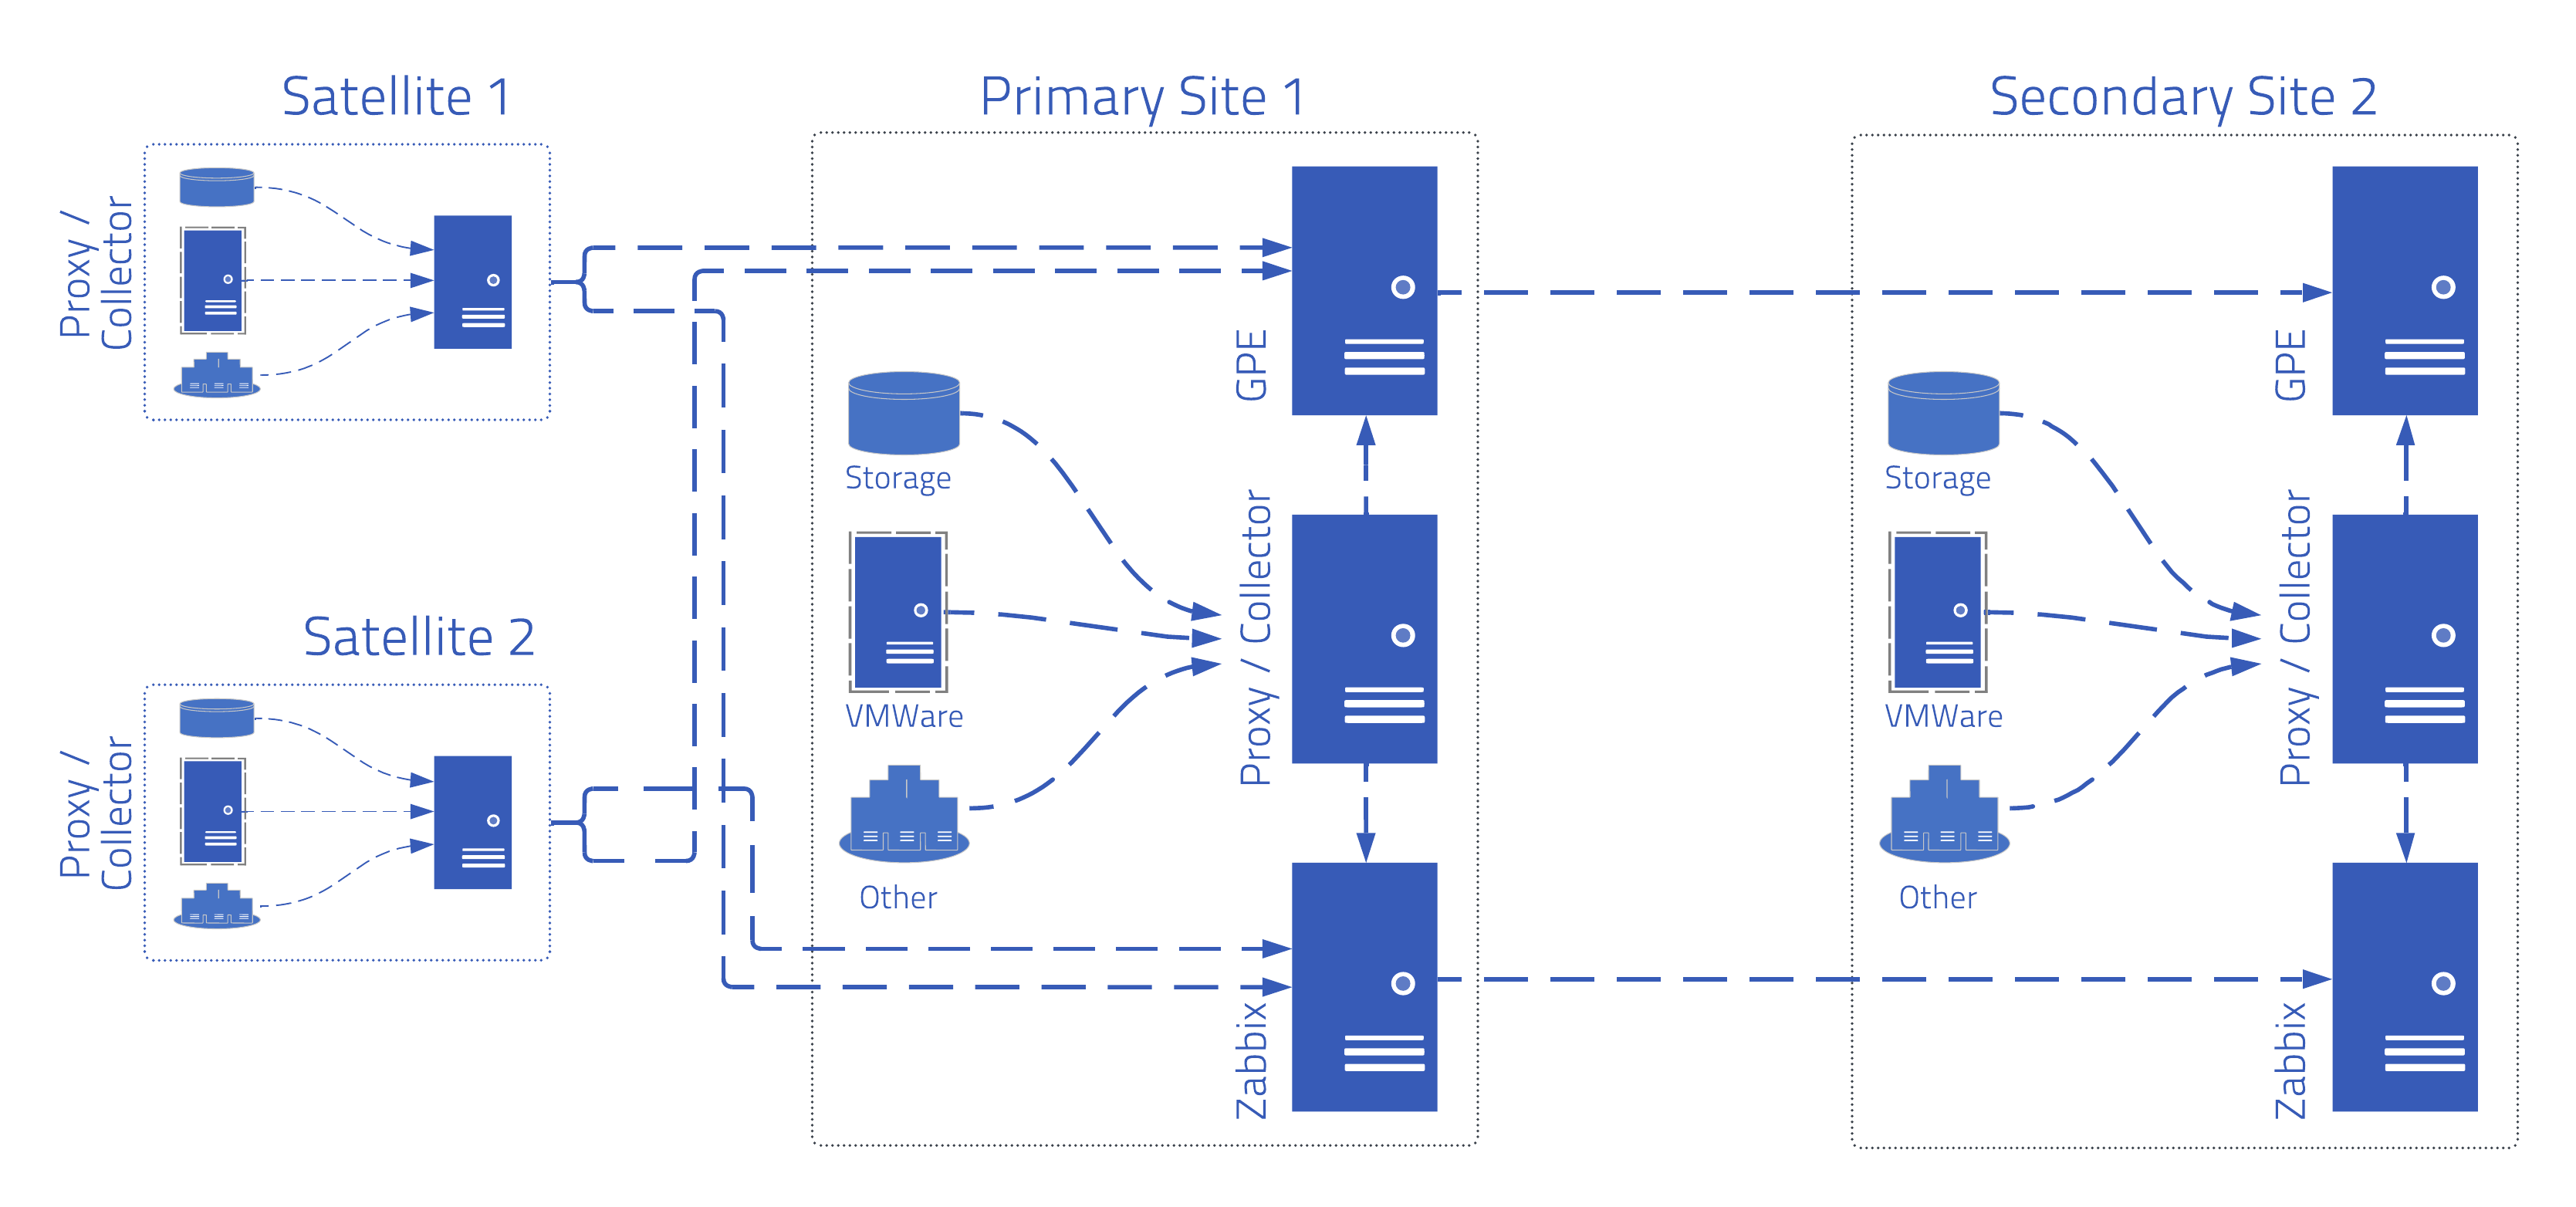
Topology at a glance

Here’s a simplified view of the architecture:
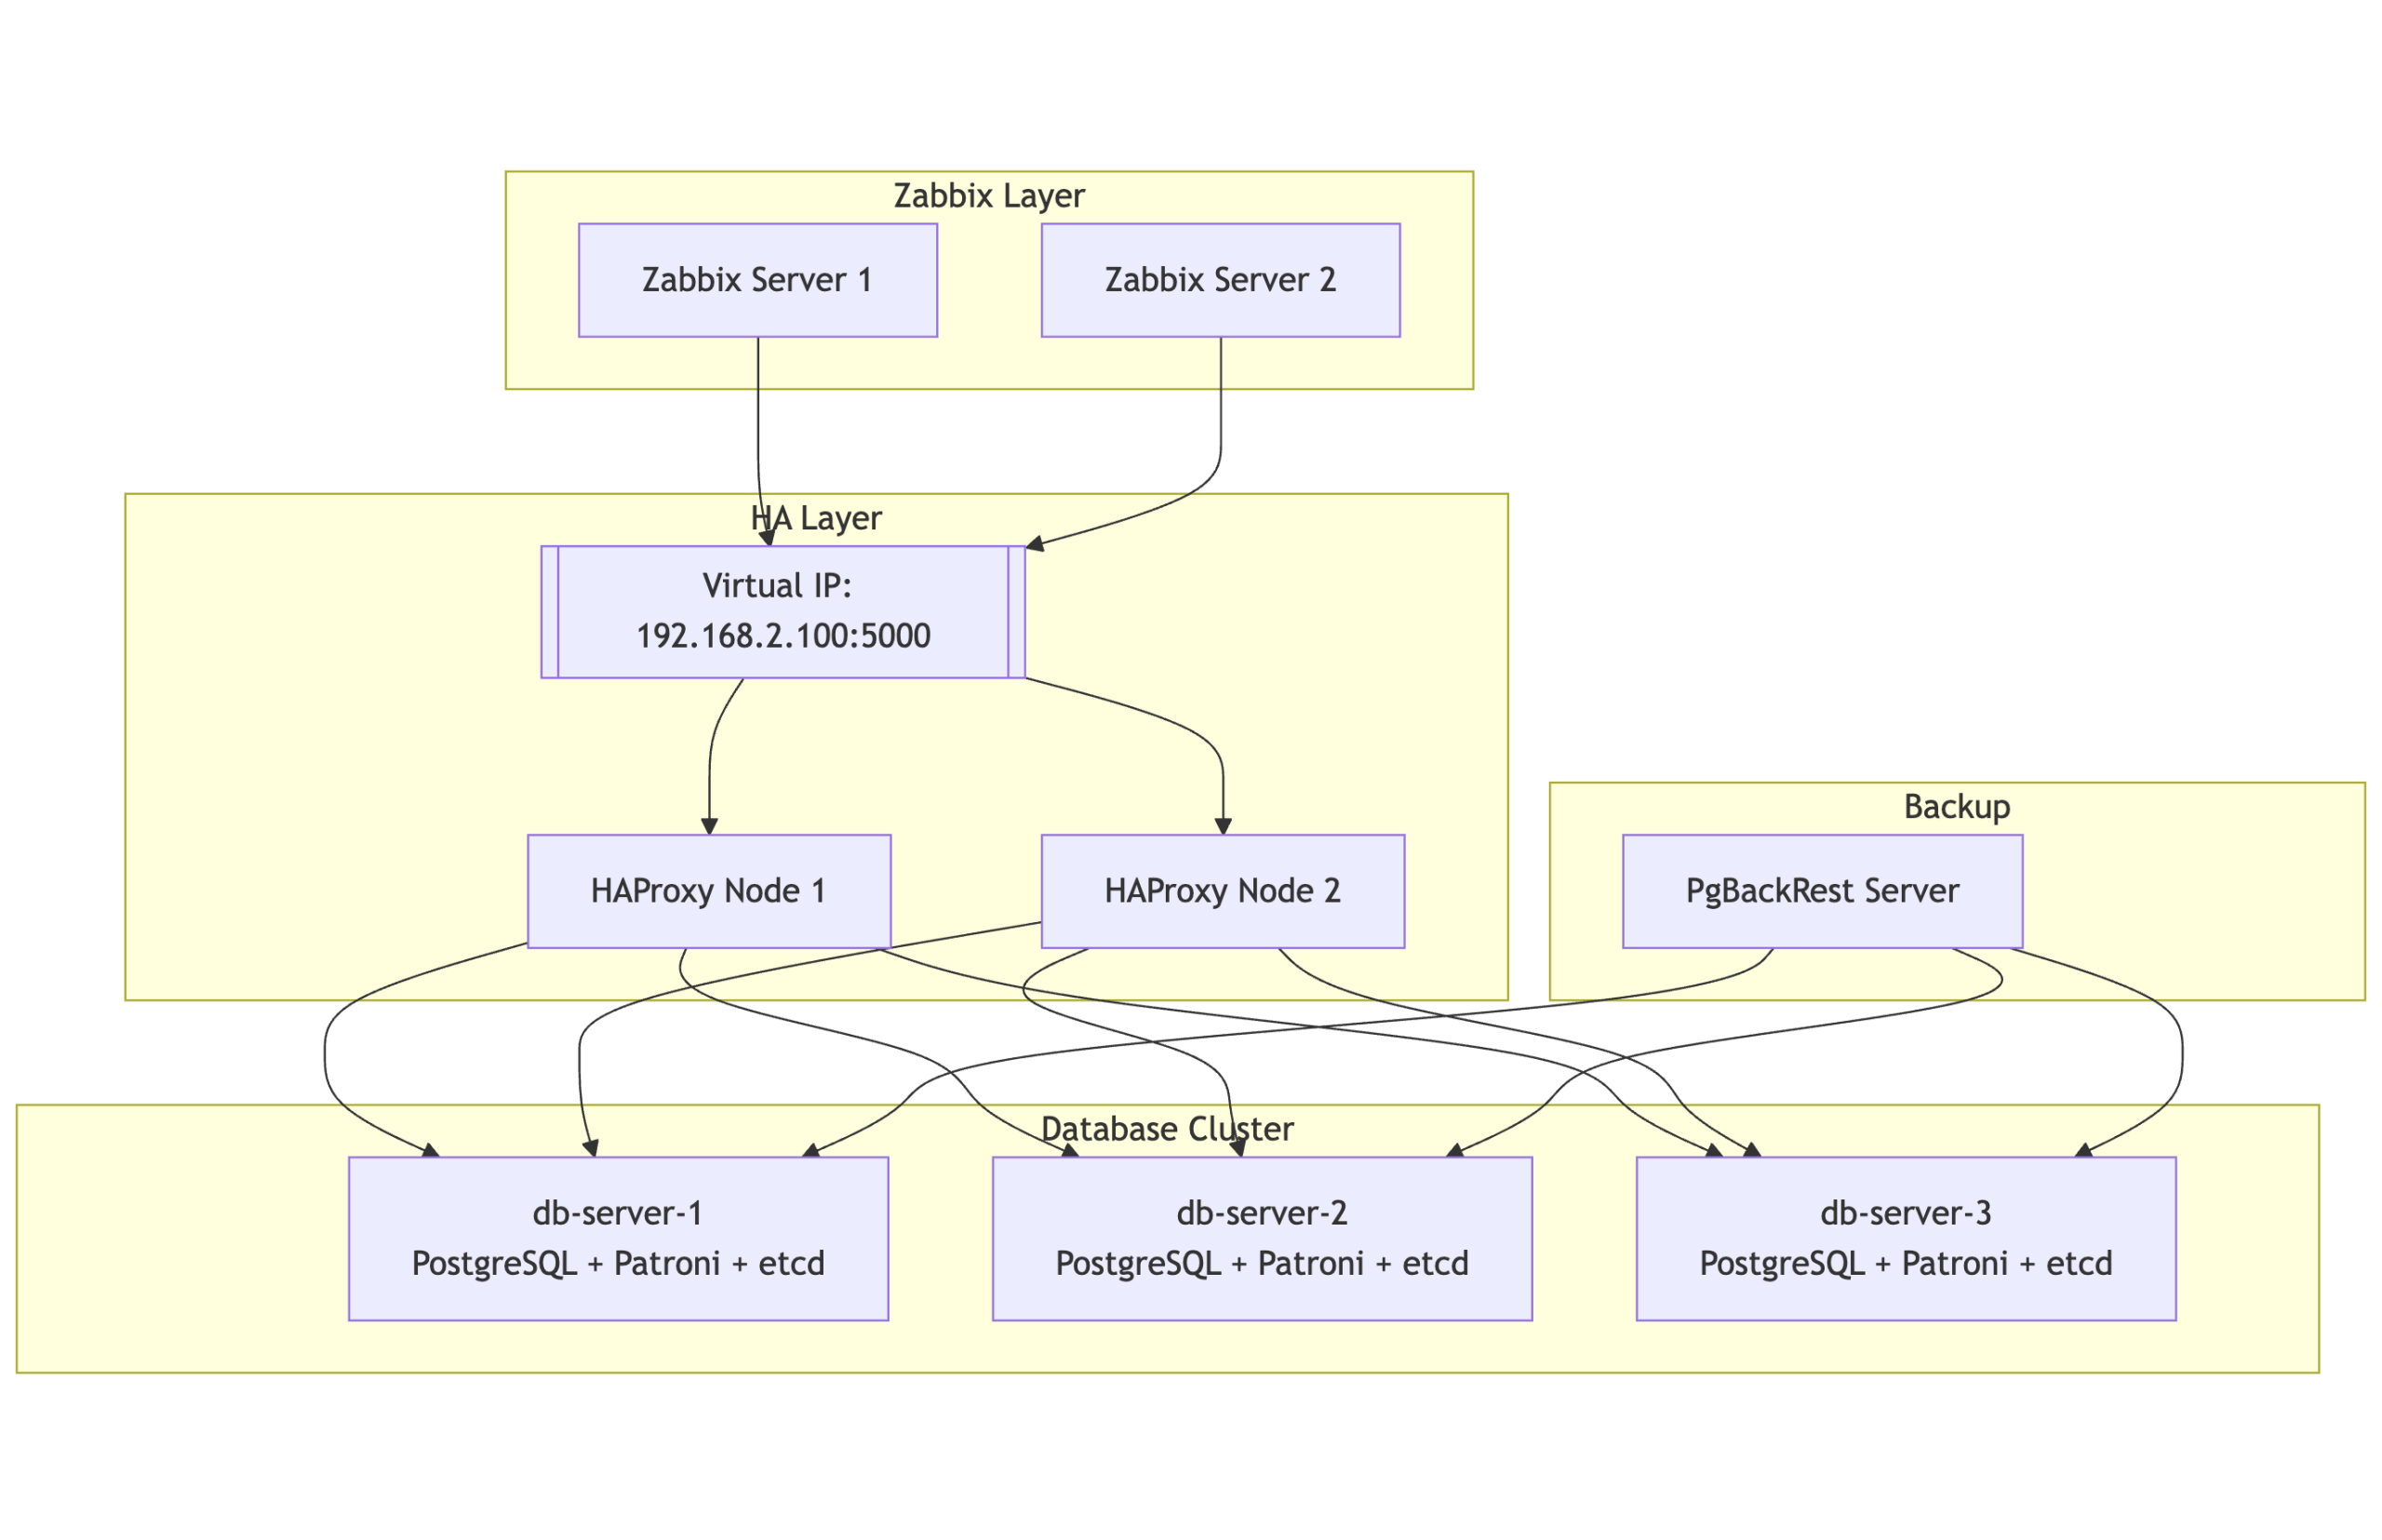
  • 2 or more database nodes (PostgreSQL + Patroni + etcd)
  • Two HAProxy nodes, each configured with Keepalived to manage a floating virtual IP
  • One backup node for PgBackRest
  • Two Zabbix servers pointing to the PostgreSQL VIP

All systems are tied together with consistent hostname mappings, time synchronization (Chrony), and service monitoring.

Notes:

  • PgBackRest is directly connected to all three PostgreSQL nodes, allowing it to archive WAL segments and pull backups regardless of which node is primary.
  • This design enables full standby backups and supports Point-In-Time Recovery (PITR).
  • HAProxy ensures Zabbix always talks to the current primary node, while Patroni and etcd handle automatic failover and cluster state management.

Design rationale

This setup prioritizes resilience and self-healing. If any single component fails a database node, a load balancer, or even a monitoring server the system continues to function.

Using Patroni with etcd ensures that failovers are handled automatically, without human intervention. HAProxy ensures client traffic is always routed to the current primary, while Keepalived ensures that this routing layer itself is highly available.

We opted for PgBackRest over simple scripts or base backups because it provides not just efficient incremental backups, but also full WAL archiving and point-in-time recovery, which are invaluable for both disaster recovery and debugging.

Lastly, we chose to integrate Zabbix itself into this HA design, treating it not just as a application but as a fully resilient service able to monitor itself, so to speak.

Real-world considerations
  • Resource planning: While our nodes run comfortably, scaling this setup to heavy workloads requires careful tuning of memory, I/O, and PostgreSQL parameters.
  • etcd placement: Although we run etcd co-located with the database nodes in this example, separating etcd onto dedicated infrastructure is ideal for large-scale environments. This avoids resource contention and preserves quorum in extreme failure scenarios.
  • Monitoring the monitors: Zabbix itself must be monitored. In our setup, each component including etcd, Patroni, and PostgreSQL exposes health endpoints that can be used by Zabbix agents or scripts to generate alerts on replication lag, cluster health, and failover events.

Conclusion

This architecture provides a solid foundation for running Zabbix in a fault-tolerant, production-ready environment. It not only ensures high availability for the database layer but also offers flexibility, observability, and operational safety.

Whether you’re running internal infrastructure monitoring or offering Zabbix as a managed service, adopting this type of HA setup removes single points of failure and gives you peace of mind — all using open-source technologies that are battle-tested and widely supported.

If you need assistance with the migration or want to ensure best practices for scaling and optimizing Zabbix, don’t hesitate to reach out to OICTS. We are a Zabbix Premium Partner operating globally, with offices in the USAUKNetherlands, and Belgium, and we’re ready to help you every step of the way.


The post Building HA Zabbix with PostgreSQL and Patroni appeared first on Zabbix Blog.

Exploring the Human Side of Software with Dylan Beatty

Post Syndicated from Michael Kammer original https://blog.zabbix.com/exploring-the-human-side-of-software-with-dylan-beatty/31320/

There are plenty of good reasons to attend Zabbix Summit 2025, but one of the most important is the fact that this year’s Summit will feature Dylan Beattie as a special guest speaker. A Software Development Consultant and Founder of Ursatile, Dylan is an international keynote speaker, and a long-time contributor to the open-source community. He’s also a Microsoft MVP and has created Rockstar, an esoteric programming language that started as an inside joke and ended up being featured in Classic Rock magazine.

At the Summit, Dylan will give a talk titled “Open Source, Open Minds. The Cost of Free Software.” We asked him about his beginnings in the tech industry, what drove the creation of Rockstar, and why communication is the key to successful software development.

Can you tell us a bit about your journey into software development? How did you get started, and was there any particular moment when you realized that you were on the right path?

Like a lot of folks in tech, I got started on the 8-bit home computers of the 1980s – mine was an Amstrad 6128, which came with a couple of fairly mediocre games, but it also had a BASIC and a LOGO interpreter, and I pretty quickly found out that writing little programs and trying to create my own games was way more fun than playing the games which were included with it. I graduated from that to a 286 PC with MS—DOS 5, Windows 3.1 – but I really wasn’t thinking about it as a career.

The turning point was when I was sixteen years old, and I was supposed to be going to university to study mathematics. Dad brought home a new 486 PC a couple of weeks before my final exams, I spent my study leave messing around on the computer instead of studying, and when I didn’t get the grades I needed for my university course I figured maybe that was a sign I should be studying computer science instead. I went to Southampton and got a bachelor’s degree in computer science, learned C, C++, Lisp, SQL, and HTML. I graduated right as the dot-com bubble was bursting but still managed to get a job building data-driven web applications, and I’ve never really looked back.

You talk a lot about the human side of software. Why do you think communication is such a critical skill in development?

One of the perennial challenges facing the craft of programming is that it can be a profoundly solitary activity. One person working on their own can create an app or a game, put it online, and share their creation with literally millions of people – no meetings, no emails, just one person cranking out code. But then you try to translate those coding skills into domains like banking, healthcare, aviation, domains where software quality can have a real, material effect on people’s lives, and you realize that the code is actually the easy part.

The ability to talk to people, figure out what they need, help them understand your own ideas; to create consensus and avoid misunderstanding? It’s way more important than being able to crank out code. The most expensive problems I’ve had to deal with in my career haven’t been bugs in the code, they’ve been misunderstandings about what the team is doing and why it matters.

How did you end up creating a programming language (Rockstar) that can do double-duty as rock lyrics?

Good question! So, there’s always been this trope of the “rockstar programmer” – these mythical, high-powered, hyper-productive developers who can crank out millions of lines of fast, flawless code – and about a decade ago there was a massive spike in recruiters putting out adverts for “rockstar programmers.” When somebody suggested on Twitter that somebody should create a programming language called Rockstar to really confuse recruiters, that gave me an idea.

Initially it was just a piece of comedy writing – a parody of a programming language specification. I wanted to see if it was possible to extract enough clichés from rock music to create a formal grammar for a Turing-complete programming language that read exactly like song lyrics. It turns out that the answer is yes! I published the parody spec on GitHub, it got shared on Reddit and Hacker News, and the whole thing snowballed from there. Eventually I had no choice but to actually build a Rockstar interpreter, which turned out to be way more difficult than I thought, but also a lot of fun. The latest version is online here  – it’s built in C#, compiles to native binaries for WIndows, Linux, and macOS, plus there’s a web assembly version on the website so curious folks can run Rockstar right in their browser without having to download anything!

Before taking on a speaking slot at this year’s Summit, how familiar were you with Zabbix? What has your experience of using it been like?

I’ve got to be honest – I’m not sure I’d ever heard of Zabbix before I was invited to speak at Zabbix Summit 2025, but that’s not unusual. I get invited to a lot of events that are focused around a particular technology or platform, and it’s a constant reminder of just how vast our industry is that somebody will organize a conference around a product I’ve never even heard of and attract literally hundreds of smart, curious people who want to share their own experiences and learn from each other. One thing about Zabbix which was particularly interesting to me when I started researching it was the licensing model. I think it’s a relatively unusual example of a commercially sustainable product or software that’s published under the Affero GPL license, so I’m really looking forward to chatting with other attendees about that and how that’s influenced their decision to use it.

You’re famous for your detailed and theatrical presentations – what makes a technical talk memorable to you?

A great talk is one that really connects with an audience, and the best way I’ve found to do that is to look for the little things that we all do every day that we’ve all learned just accept at face value, even when we have no idea why they work that way. Why is a capital “A” ASCII code 65 but a lowercase “a” is code 97? Why is validating email addresses difficult? Why is vertically aligning something in CSS such a big deal? There’s a good chance that a lot of folks in the audience have asked themselves that same question at some point, so the curiosity is already there. Tapping into that curiosity gets their attention, and then you can tell them the good stuff: the history, the stories, the personalities, the decisions.

There’s a lot of stuff in tech which feels kinda stupid, but none of it was designed to be stupid (well, except Rockstar!) Once you understand the context and the history, everything makes a lot more sense – and then at some point, maybe months later, you’ll hit a weird text encoding bug, or a problem with a system that won’t accept certain kinds of email addresses, and you’ll remember the talk. I get email from folks sometimes talking about how something from one of my presentations has helped them fix a weird bug years after they saw the presentation. That’s a great feeling.

Can you drop any hints about your presentation at this year’s Summit? What should audience members expect?

Sure! We’re going to talk about MIT, laser printers, software, Commander Keen, Doom, Quake, Netscape, the origins of the term “open source”, Linksys routers, WordPress, how the xz-utils backdoor nearly ended up compromising about half the computers on the internet – and a really cute story about a squirrel. It’s going to be awesome. I can’t wait!


The post Exploring the Human Side of Software with Dylan Beatty appeared first on Zabbix Blog.

Migrating from PRTG to Zabbix: A High-Level Guide

Post Syndicated from Patrik Uytterhoeven original https://blog.zabbix.com/migrating-from-prtg-to-zabbix-a-high-level-guide/30845/

For companies looking to migrate from PRTG Network Monitor to Zabbix, one of the most critical aspects is making sure a smooth migration of monitored devices and configurations. While there is no official tool to directly migrate between the two platforms, creating a bridge using custom export/import scripts allows for an effective and large migation. This blog post outlines a practical approach to achieving that migration based on the export/import methodology we at Opensource ICT Solutions previously implemented for one of our clients.

Why migrate?

While PRTG offers an intuitive interface and is popular for its ease of use, Zabbix provides:

  • Greater flexibility and scalability
  • Full open-source licensing
  • More powerful automation and templating
  • A robust API for integrations
  • Lower costs, especially since Paessler was sold to an investor

These features make Zabbix an attractive choice for teams looking to scale or standardize on open-source infrastructure.

Migration overview

The migration involves two key steps:

  1. Exporting PRTG device information
  2. Importing data into Zabbix

Because the two systems are conceptually and structurally different, we focused our scripts on migrating what is most transferable: device names, IP addresses, and interface types. SNMP versions or PRTG-specific sensor details were excluded or simplified where not applicable to Zabbix. PRTG, for example, will only export probes that have an OID that was not built-in in PRTG but added later, making our export incomplete. This does not mean we did a partial migration, it just means we have not included it in the automated approach.

Step 1: Exporting from PRTG

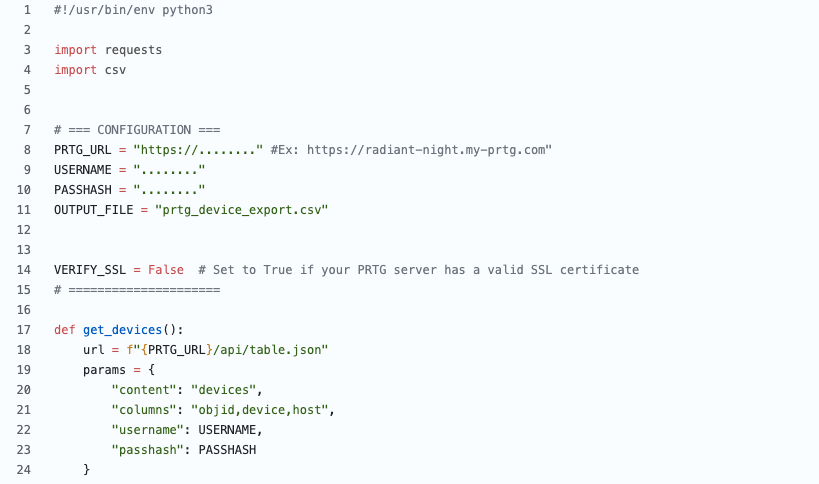
We developed a Python-based script that interacts with the PRTG API to extract monitored device data and export it to a CSV file. The script filters out irrelevant objects and organizes the output for easy Zabbix processing.

This creates a clean CSV, like this:

Device Name, IP Address, Interface Type
zabbix-server,10.0.0.10,agent
ServerA,192.168.0.2,SNMP
ServerA,192.168.0.2,agent
core-switch,192.168.0.1,SNMP

This file serves as a clean, structured inventory of monitored devices.

Note: SNMP version fields were excluded in the final export, as Zabbix does not currently display or rely on an SNMP version in the same way PRTG does.

Step 2: Importing into Zabbix

Using Zabbix’s API, we created an import script that reads the CSV and:

  • Creates host entries
  • Assigns them to the appropriate host group
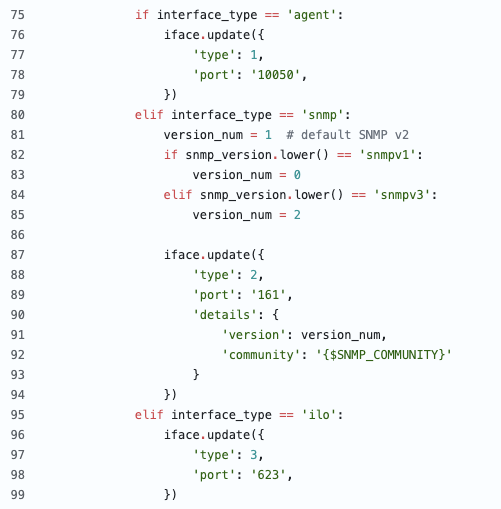
  • Adds relevant interfaces (e.g., Agent,ILO,SNMP or a combination of …)

Each host is configured based on its detected interface type in PRTG.

On the Zabbix side, we used the Zabbix API to automate the creation of hosts, interfaces, and template assignment. The import script reads the CSV line-by-line and takes action based on the interface type.

Considerations and “gotchas”

  • Templates: We didn’t add templates, as there is no 1:1 solution – PRTG has a different concept and adding a standard template would be possible but probably not the best solution.
  • Host Groups: For ease of use and the limited time we had, we added all hosts in a temporary host group made for the migration. Although we do have scripts that take it out from PRTG and create it in Zabbix, in this particular migration it was not needed.
  • Permissions: The API token used in the import script must have sufficient privileges to create hosts.

What is NOT migrated

Because of fundamental differences between the platforms, the following are not directly migrated:

  • Historical data or sensor readings: Mainly because the customer had no hard requirement for it.
  • Custom PRTG notifications or dependencies: It was easier to manually re-create them.
  • Maps or dashboards: The Zabbix approach is so different that it was easier to recreate it manually (and improve).
  • Sensors: Zabbix is working with a different concept.

Post-migration tips

  • Validation: After the import, verify that each host is reachable and monitored correctly in Zabbix.
  • Discovery: Consider using Zabbix’s LLD (Low-Level Discovery) to dynamically find interfaces, disks, or other entities.
  • Housekeeping: Disable PRTG monitoring only after confirming Zabbix is fully operational.

Conclusion

Migrating from PRTG to Zabbix is not a one click operation, but with some scripting, planning, and experience from a partner like us, it can be done efficiently and with minimal disruption. The custom export/import scripts act as a reliable bridge between the two systems, allowing for a clean transfer of your monitoring inventory. From there, Zabbix’s automation and scalability features can help take your monitoring to the next level.

If you need assistance with the migration or want to ensure best practices for scaling and optimizing Zabbix, don’t hesitate to reach out to OICTS. We are a Zabbix Premium Partner operating globally, with offices in the USA, UK, Netherlands, and Belgium ready to help you every step of the way.

The post Migrating from PRTG to Zabbix: A High-Level Guide appeared first on Zabbix Blog.

Troubleshooting network connectivity and performance with Cloudflare AI

Post Syndicated from Chris Draper original https://blog.cloudflare.com/AI-troubleshoot-warp-and-network-connectivity-issues/

Monitoring a corporate network and troubleshooting any performance issues across that network is a hard problem, and it has become increasingly complex over time. Imagine that you’re maintaining a corporate network, and you get the dreaded IT ticket. An executive is having a performance issue with an application, and they want you to look into it. The ticket doesn’t have a lot of details. It simply says: “Our internal documentation is taking forever to load. PLS FIX NOW”.

In the early days of IT, a corporate network was built on-premises. It provided network connectivity between employees that worked in person and a variety of corporate applications that were hosted locally.

The shift to cloud environments, the rise of SaaS applications, and a “work from anywhere” model has made IT environments significantly more complex in the past few years. Today, it’s hard to know if a performance issue is the result of:

  • An employee’s device

  • Their home or corporate wifi

  • The corporate network

  • A cloud network hosting a SaaS app

  • An intermediary ISP

A performance ticket submitted by an employee might even be a combination of multiple performance issues all wrapped together into one nasty problem.

Cloudflare built Cloudflare One, our Secure Access Service Edge (SASE) platform, to protect enterprise applications, users, devices, and networks. In particular, this platform relies on two capabilities to simplify troubleshooting performance issues:

  • Cloudflare’s Zero Trust client, also known as WARP, forwards and encrypts traffic from devices to Cloudflare edge.

  • Digital Experience Monitoring (DEX) works alongside WARP to monitor device, network, and application performance.

We’re excited to announce two new AI-powered tools that will make it easier to troubleshoot WARP client connectivity and performance issues.  We’re releasing a new WARP diagnostic analyzer in the Zero Trust dashboard and a MCP (Model Context Protocol) server for DEX. Today, every Cloudflare One customer has free access to both of these new features by default.

WARP diagnostic analyzer

The WARP client provides diagnostic logs that can be used to troubleshoot connectivity issues on a device. For desktop clients, the most common issues can be investigated with the information captured in logs called WARP diagnostic. Each WARP diagnostic log contains an extensive amount of information spanning days of captured events occurring on the client. It takes expertise to manually go through all of this information and understand the full picture of what is occurring on a client that is having issues. In the past, we’ve advised customers having issues to send their WARP diagnostic log straight to us so that our trained support experts can do a root cause analysis for them. While this is effective, we want to give our customers the tools to take control of deciphering common troubleshooting issues for even quicker resolution. 

Enter the WARP diagnostic analyzer, a new AI available for free in the Cloudflare One dashboard as of today! This AI demystifies information in the WARP diagnostic log so you can better understand events impacting the performance of your clients and network connectivity. Now, when you run a remote capture for WARP diagnostics in the Cloudflare One dashboard, you can generate an AI analysis of the WARP diagnostic file. Simply go to your organization’s Zero Trust dashboard and select DEX > Remote Captures from the side navigation bar. After you successfully run diagnostics and produce a WARP diagnostic file, you can open the status details and select View WARP Diag to generate your AI analysis.


In the WARP Diag analysis, you will find a Cloudy summary of events that we recommend a deeper dive into.


Below this summary is an events section, where the analyzer highlights occurrences of events commonly occurring when there are client and connectivity issues. 


Expanding on any of the events detected will reveal a detailed page explaining the event, recommended resources to help troubleshoot, and a list of time stamped recent occurrences of the event on the device.


To further help with trouble shooting we’ve added a Device and WARP details section at the bottom of this page with a quick view of the device specifications and WARP configurations such as Operating system, WARP version, and the device profile ID.


Finally, we’ve made it easy to take all the information created in your AI summary with you by navigating to the JSON file tab and copying the contents. Your WARP Diag file is also available to download from this screen for any further analysis.


MCP server for DEX

Alongside the new WARP Diagnostic Analyzer, we’re excited to announce that all Cloudflare One customers have access to a MCP (Model Context Protocol) server for our Digital Experience Monitoring (DEX) product. Let’s dive into how this will save our customers time and money.

Cloudflare One customers use Digital Experience Monitoring (DEX) to monitor devices across their employee network and troubleshoot any connectivity or performance issues. Like many products at Cloudflare, every data point generated by DEX is available to customers via Cloudflare’s API or log ingestion. DEX API and log data is valuable because it enables Enterprises to create custom analytics for their devices’ connectivity and performance in a SIEM (Security Information and Event Management). Building new data pipelines and various dashboards can take a lot of time and can be expensive. Some of Cloudflare One customers aren’t able to dedicate the engineering time to build custom analytics: whether it’s due to budget, resource constraints, time constraints, or other factors.

Model Context Protocol (MCP) is an AI standardization that allows AI to connect to other applications. In this instance, using MCP together with DEX gives users a custom analytics experience — without all the work of integrating log data into a SIEM. Network security practitioners can type out a question (like “Show me the performance data for [email protected]’s device in a few graphs”), and an MCP server will answer that question with a customized graph on Alice’s device data from the DEX API.

Troubleshooting DNS query performance with the DEX MCP server

Any IT admin, security engineer, or network engineer can ask the MCP server a question like: “I received an IT ticket from [email protected] who is an enterprise employee. He is complaining about the performance of his device. Can you investigate this for me?”.

After you submit this question, the DEX MCP server will start by reviewing the device’s overall health.

Overall Device Health:
✅ Connection Status: Consistently connected for the past 24 hours with 100% availability
✅ WARP Mode: Running in optimal "warp+doh" (WARP + DNS over HTTPS) mode
✅ Client Version: Up-to-date with version 2025.1.7.2

So far, the device’s health looks great. Next, the DEX MCP server will begin analyzing the results of the performance tests that are configured on Bob’s device.

📊 Performance Metrics Analysis

HTTP Response Times:
Google.com test: Average 247ms (Range: 81-649ms)
  • Shows significant improvement throughout the day: Started at ~317ms, dropped to ~211ms by evening
Wiki.internal.acme.com: Average 1,374ms (Range: 877-2,431ms)
  • This is notably high and could be the source of performance complaints
  • DNS resolution particularly slow: Average 616ms with spikes up to 1,600ms

Now we’re making progress in our troubleshooting effort. The DEX MCP server identified that the HTTP GET test for wiki.internal.acme.com has a high average resource fetch time when compared to other websites (like google.com). In particular, high resource fetch time is the result of slow DNS resolution. Now, the DEX MCP server will summarize its findings.

🚨 Performance Issues Identified
Extremely Slow DNS Resolution:
  • Average DNS response time of 616ms is significantly high
  • Normal DNS should be <50ms for good performance
High Resource Fetch Times on wiki.internal.acme.com:
   • 1.3+ second response times indicate potential application-level issues
   • Could be related to DNS performance or server-side delays
HTTP Status Code Issues:
        • wiki.internal.acme.com is showing consistent HTTP 400 errors
        • This suggests potential configuration or routing issues

Now, we’ve successfully identified that Bob’s slow wiki performance is the result of a high average DNS response time. Slow DNS resolution increases the average resource fetch time, and also generates HTTP 400 errors for Enterprise employees that are attempting to access wiki.internal.acme.com. Notably, it’s likely that if the wiki is seeing slow DNS response times, other internal applications are experiencing performance issues as well.

We can ask the DEX MCP server to suggest potential solutions that would fix this wider DNS performance issue.

🔧 DNS Optimization Strategies

Check WARP DNS configuration and settings
  • Since the device is using WARP+DoH mode, you can optimize the DNS settings
Implement or improve local DNS caching
  • Implement or improve local DNS caching to reduce repeated lookups
Network stack tuning
  • Optimize TCP / UDP settings for DNS

Try out the DEX MCP server today

Fast and easy option for testing an MCP server

Any Cloudflare One customer with a Free, PayGo, or ENT plan can start using the DEX MCP server in less than one minute. The fastest and easiest way to try out the DEX MCP server is to visit playground.ai.cloudflare.com. There are five steps to get started:

  1. Copy the URL for the DEX MCP server: https://dex.mcp.cloudflare.com/sse

  2. Open playground.ai.cloudflare.com in a browser

  3. Find the section in the left side bar titled MCP Servers

  4. Paste the URL for the DEX MCP server into the URL input box and click Connect

  5. Authenticate your Cloudflare account, and then start asking questions to the DEX MCP server

It’s worth noting that end users will need to ask specific and explicit questions to the DEX MCP server to get a response. For example, you may need to say, “Set my production account as the active  account”, and then give the separate command, “Fetch the DEX test results for the user [email protected] over the past 24 hours”.

Better experience for MCP servers that requires additional steps

Customers will get a more flexible prompt experience by configuring the DEX MCP server with their preferred AI assistant (Claude, Gemini, ChatGPT, etc.) that has MCP server support. MCP server support may require a subscription for some AI assistants. You can read the Digital Experience Monitoring – MCP server documentation for step by step instructions on how to get set up with each of the major AI assistants that are available today.

As an example, you can configure the DEX MCP server in Claude by downloading the Claude Desktop client, then selecting Claude Code > Developer > Edit Config. You will be prompted to open “claude_desktop_config.json” in a code editor of your choice. Simply add the following JSON configuration, and you’re ready to use Claude to call the DEX MCP server.

{
  "globalShortcut": "",
  "mcpServers": {
    "cloudflare-dex-analysis": {
      "command": "npx",
      "args": [
        "mcp-remote",
        "https://dex.mcp.cloudflare.com/sse"
      ]
    }
  }
}

Get started with Cloudflare One today

Are you ready to secure your Internet traffic, employee devices, and private resources without compromising speed? You can get started with our new Cloudflare One AI powered tools today.

The WARP diagnostic analyzer and the DEX MCP server are generally available to all customers. Head to the Zero Trust dashboard to run a WARP diagnostic and learn more about your client’s connectivity with the WARP diagnostic analyzer. You can test out the new DEX MCP server (https://dex.mcp.cloudflare.com/sse) in less than one minute at playground.ai.cloudflare.com, and you can also configure an AI assistant like Claude to use the new DEX MCP server.

If you don’t have a Cloudflare account, and you want to try these new features, you can create a free account for up to 50 users. If you’re an Enterprise customer, and you’d like a demo of these new Cloudflare One AI features, you can reach out to your account team to set up a demo anytime. 

You can stay up to date on latest feature releases across the Cloudflare One platform by following the Cloudflare One changelogs and joining the conversation in the Cloudflare community hub or on our Discord Server.


Zabbix at the Zhongnan University of Economics and Law

Post Syndicated from Michael Kammer original https://blog.zabbix.com/zabbix-at-the-zhongnan-university-of-economics-and-law/30949/

Zhongnan University of Economics and Law (ZUEL), located in Wuhan City, Hubei Province, China, is a key university with two campuses – Nanhu and Shouyi. The school boasts over 20,000 full-time undergraduate students, more than 8,800 graduate students, and over 2,500 faculty and staff members. ZUEL enjoys an outstanding reputation in the fields of law and economics, with four national key disciplines. Its law discipline, meanwhile, has been included in the list of national “Double First-Class” disciplines.

The challenge

As the information infrastructure at ZUEL continues to expand, the scale of the university’s IT infrastructure has rapidly grown to encompass power systems, dynamic environmental systems, servers, network devices, security appliances, storage systems, virtualization platforms, operating systems, databases, data lakes, and campus application systems.

At the same time, the daily academic and administrative activities of faculty and students increasingly demand higher levels of stability and reliability from information systems. To ensure the efficient operation of these systems, the Information Management department needed a monitoring and management system that could cover the entire university’s IT resources and address the growing complexities of operational maintenance.

The university found that traditional monitoring and management systems often fall short when faced with such large-scale and diverse monitoring demands, revealing problems like insufficient monitoring points, poor real-time capabilities, and limited scalability. To address these challenges, the university decided to adopt Zabbix 7.0 and develop a custom IP Radar platform to further meet its refined operational maintenance needs.

The solution

When combined with Zabbix 7.0, the IP Radar system can achieve comprehensive monitoring and management of the university’s entire IT infrastructure through the integrated application of multiple monitoring protocols and technologies. Specifically, the system collects data and performs monitoring with the help of the following core technologies:

  • Zabbix 7.0. As an enterprise-level open-source monitoring platform renowned for its robust data collection and analysis capabilities, Zabbix enhances the system’s high availability, supporting large-scale concurrent processing to make sure that the monitoring system remains stable and delivers uninterrupted service even under heavy loads.
  • Parallel monitoring with multiple protocols. The system collects data through a variety of protocols, including Agent, SNMP, IPMI, MODBUS, MQTT, and more, enabling the real-time monitoring of a wide variety of IT hardware.
  • High-availability design. To accommodate the monitoring demands of massive devices and thousands of users, the Zabbix 7.0 platform supports multi-node deployment and redundancy design, enabling load balancing and failover among proxy servers. Even in the event of a node failure, the system maintains uninterrupted monitoring services, and it’s also equipped with an automated fault alerting and repair mechanism.
  • The self-developed IP Radar platform. To meet a demanding set of operation and maintenance management needs, ZUEL has developed the IP Radar system based on the Zabbix 7.0 platform, further customizing its business monitoring capabilities. IP Radar not only conducts real-time monitoring of the IT infrastructure, but it also provides detailed performance analysis reports and trend predictions, while integrating behavior monitoring capabilities to enhance the school’s network security management.

The IP Radar platform itself contains a variety of unique and innovative features, including:

  • Comprehensive monitoring coverage. The IP Radar system monitors over a million items – everything from hardware devices to application systems, affecting everything from network performance to user experience. This extensive coverage gives the Information Management department to a comprehensive understanding of the operational status of the school’s IT resources while providing sufficient data support for troubleshooting and performance optimization.
  • Customized monitoring strategies. Compared to traditional monitoring systems, IP Radar offers highly customized monitoring strategies. ZUEL can tailor different business dashboards for networks, computing resources, user experience, data center environments, and more, based on its own needs and the permissions granted to operation and maintenance personnel. Depending on different monitoring thresholds and alerting strategies, the system can automatically generate alerts and notify relevant personnel through enterprise WeChat, SMS, and other channels.
  • Intelligent alerting and automated handling. The intelligent alerting system of the IP Radar platform leverages machine learning algorithms to analyze historical monitoring data, enabling it to predict potential fault risks and issue early warnings. At the same time, the system integrates automated operation and maintenance capabilities, which allow it to automatically execute predetermined repair operations when certain common faults occur, reducing the time and cost of manual intervention.
  • Network security monitoring. In terms of network security, the IP Radar system is capable of identifying abnormal traffic patterns and promptly detecting potential security threats through real-time analysis of the school’s entire network traffic. The system also supports the monitoring of online behavior to ensure that network access activities comply with the school’s security policies.

The results

After implementing the Zabbix-based system, ZUEL was able to measure a wide range of monitoring performance improvements, including:

  • Improved operational and maintenance efficiency. Through the IP Radar system, the school’s Information Management department has been able to monitor the operational status of over 28,000 hosts in real-time, significantly enhancing operational efficiency. The system’s automated fault handling capabilities reduce the complexity of manual operations, allowing operations and maintenance personnel to focus on addressing only the complex issues that the system is unable to resolve automatically. At the same time, the system’s intelligent alerting feature enables the early detection of potential problems, preventing sudden failures.
  • Enhancing system stability and reliability. The high availability design of Zabbix 7.0 ensures that the system remains stable even under heavy loads. Its redundant design and automatic failover mechanisms guarantee the reliability of the system, and the trend analysis functionality provided by IP Radar helps administrators to identify factors that may affect system stability in advance and making corresponding adjustments, enhancing the overall reliability of the IT system in the process.
  • Advancing detailed information management. The IP Radar platform lets schools manage multiple IT resources with greater precision. The system not only monitors the operational status of hardware devices, but it also analyzes the performance of business systems, helping administrators to optimize system configurations and enhancing user experiences. During project development, historical data from the monitoring platform serves as an essential basis for decision-making. In the acceptance phase, the monitoring platform provides evaluation reference data for operational efficiency and stability.

The IP Radar monitoring and management system developed by ZUEL and based on Zabbix 7.0 has become the largest, most widely used, and most effective (in terms of the volume of monitored data) in the Chinese education sector. The successful implementation of this system not only provides strong support for the school’s information management, but it also offers valuable references for information operation and maintenance at other universities.

In conclusion

Looking ahead, the IP Radar system is poised to expand its functionalities further by integrating more intelligent operation and maintenance management tools. Through the introduction of emerging technologies such as big data analysis and artificial intelligence, the system will achieve more breakthroughs in areas like automated operation and maintenance as well as intelligent fault prediction, providing even more comprehensive technical support for the university’s information management.

To learn more about what Zabbix can do for educational institutions, visit our website.


The post Zabbix at the Zhongnan University of Economics and Law appeared first on Zabbix Blog.

Understanding HTTP Template Authorization in AWS

Post Syndicated from evgenii.gordymov original https://blog.zabbix.com/understanding-http-template-authorization-in-aws/30856/

Authorization in Amazon Web Services (AWS) determines what actions a user, service, or system can perform on resources. It answers the question: “Does this identity have permission to do this action on that resource?”

In AWS, authorization is primarily handled through:

  • IAM (Identity and Access Management) policies
  • Resource-based policies (like S3 bucket policies)
  • Session-based permissions (like STS AssumeRole)

What authorization types are available in Zabbix AWS templates?

  • Access key authorization
  • Role-based authorization
  • Assume role authorization

Let’s look briefly at each of them.

Before using the template, you need to create an IAM policy that grants the necessary permissions for the AWS services the template will interact with.

This policy defines what actions are allowedon which resources, and optionally, under which conditions. Once created, the policy should be attached to the IAM role or user that will run the template.

IAM policy for Zabbix

Add the following required permissions to your Zabbix IAM policy in order to collect metrics. The policy can change when new metrics and services are added in Zabbix templates.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Action": [
                "cloudwatch:DescribeAlarms",
                "cloudwatch:GetMetricData",
                "ec2:DescribeInstances",
                "ec2:DescribeVolumes",
                "ec2:DescribeRegions",
                "rds:DescribeEvents",
                "rds:DescribeDBInstances",
                "ecs:DescribeClusters",
                "ecs:ListServices",
                "ecs:ListTasks",
                "ecs:ListClusters",
                "s3:ListAllMyBuckets",
                "s3:GetBucketLocation",
                "s3:GetMetricsConfiguration",
                "elasticloadbalancing:DescribeLoadBalancers",
                "elasticloadbalancing:DescribeTargetGroups",
                "ec2:DescribeSecurityGroups",
                "lambda:ListFunctions"
            ],
            "Effect": "Allow",
            "Resource": "*"
        }
    ]
}

To create and attach the policy:

  • Go to IAM → Policies → Create policy
  • Choose JSON and paste your policy
  • Review and create the policy

Access key authorization

1. Attach the required policy to the IAM user

  • Go to IAM → Users → Select a user → Permissions tab
  • Click Attach policies
  • Select the policy you created before (IAM Policy for Zabbix)
  • Click Attach policy

2. Get your access key and secret access key

In the AWS console:

  • Go to IAM → Users → Select a user → Security credentials tab

  • Click Create access key

  • Copy:

    • Access key ID
    • Secret access key

⚠ Never expose your keys publicly!
3. Configure AWS CLI

Open your terminal and run:

configure aws cli

aws configure --profile zabbix_user

You’ll be prompted to enter:

AWS Access Key ID [None]: AKIAXXXXXXXXXXXEXAMPLE
AWS Secret Access Key [None]: asdkjhUSADWDskhjdasd/EXAMPLEKEY
Default region name [None]: eu-central-1
Default output format [None]: json

4. Test it

List all S3 buckets:

aws s3 ls --profile zabbix_user

Get EC2 tags:

Use region where you create instance

aws ec2 describe-instances --region eu-central-1 --query 'Reservations[*].Instances[*].Tags' --profile zabbix_user

If you get this error…

An error occurred (AccessDenied) when calling the DescribeInstances operation: User: arn:aws:iam::123456789010:user/zabbix_user is not authorized to perform: ec2:DescribeInstances on resource: arn:aws:ec2:eu-central-1:123456789010:instance/*

…you need to check the following permission to the role you are using (IAM Policy for Zabbix).

5. Set the following macros in Zabbix:

  • {$AWS.AUTH_TYPE} – set to access_key
  • {$AWS.ACCESS.KEY.ID} – set to your access key ID
  • {$AWS.SECRET.ACCESS.KEY} – set to your secret access key

Security tips

  • Never hardcode access keys in scripts or code.
  • Store them in ~/.aws/credentials, which is protected by file system permissions.
  • Apply least privilege with IAM policies.

Role-based authorization

1. Add the appropriate permission to the role you are using:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": "iam:PassRole",
            "Resource": "arn:aws:iam::{Account}:role/{RoleNameWithPath}"
        },
        {
            "Effect": "Allow",
            "Action": [
                "theSameAsIAMPolicyForZabbix",
            ],
            "Resource": "*"
        }
    ]
}

2. Add a principal to the trust relationships of the role you are using:

  • Go to IAM → Roles → Select a role → Trust relationships tab
  • Click Edit trust relationship
  • Add a principal to the trust relationships of the role you are using:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Service": [
                    "ec2.amazonaws.com"
                ]
            },
            "Action": [
                "sts:AssumeRole"
            ]
        }
    ]
}

⚠ Using role-based authorization is only possible when you use a Zabbix server or proxy inside AWS.

3. Attach the role to the instance

  • Go to EC2 → Instances → Select an instance → Actions → Security → Modify IAM role
  • Select the role you created before which has the policy attached (IAM Policy for Zabbix)
  • Click Apply

4. Test it

Connect to ES2 ssh terminal in instance and run:

  • Go to EC2 → Instances → Select an instance → Connect → SSH client

Example:

ssh -i "zabbix_user.pem" [email protected]

Get caller identity:

aws sts get-caller-identity

Get token for metadata service:

export TOKEN=$(curl -X PUT "http://169.254.169.254/latest/api/token" -H "X-aws-ec2-metadata-token-ttl-seconds: 21600")

Get IAM role from metadata service:

curl -H "X-aws-ec2-metadata-token: $TOKEN" http://169.254.169.254/latest/meta-data/iam/security-credentials

Get IAM role credentials from metadata service using role name from instance metadata service (see Get IAM role from metadata service):

curl -H "X-aws-ec2-metadata-token: $TOKEN" http://169.254.169.254/latest/meta-data/iam/security-credentials/<<--role_name-->>

6. Set the following macros in Zabbix:

  • {$AWS.AUTH_TYPE} – set to role_base
  • {$AWS.ASSUME.ROLE.ARN} – set to your role ARN

Assume role authorization

This method has two options:

  • Using access key authorization for getting creds for assume role
  • Using role-based authorization for getting creds for assume role

Lets look first at using access key authorization for getting creds for assume role.

Using access key authorization for getting creds for assume role

1. Create access key for user (see Access Key Authorization)

2. Add the appropriate permission in role you are using:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": "sts:AssumeRole",
            "Resource": "arn:aws:iam::{Account}:user/{UserName}"
        },
        {
            "Effect": "Allow",
            "Action": [
                "theSameAsIAMPolicyForZabbix",
            ],
            "Resource": "*"
        }
    ]
}

3. Add principal to the trust relationships of the role you are using:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "AWS": "arn:aws:iam::{Account}:user/{UserName}"
      },
      "Action": "sts:AssumeRole"
    }
  ]
}


4. Test It

Get assume role credentials using access key authorization

aws sts assume-role --role-arn arn:aws:iam::123456789010:role/Zabbix_Role --role-session-name test-session --profile zabbix_user

An example of response:

{
    "Credentials": {
        "AccessKeyId": "ASDFGHJKLEXAMPLE",
        "SecretAccessKey": "QowihdwoieuoinflksnliooEXAMPLE",
        "Expiration": "2029-09-09T22:22:22+00:00"
    },
    "AssumedRoleUser": {
        "AssumedRoleId": "ASDFGHJKLEXAMPLE:test-session",
        "Arn": "arn:aws:sts::123456789010:assumed-role/Zabbix_Role/test-session"
    }
}

5. Set the following macros in Zabbix:

  • {$AWS.AUTH_TYPE} – set to assume_role
  • {$AWS.ACCESS.KEY.ID} – set to your access key ID
  • {$AWS.SECRET.ACCESS.KEY} – set to your secret access key
  • {$AWS.ASSUME.ROLE.ARN} – set to your role ARN
  • {$AWS.ASSUME.ROLE.AUTH.METADATA} – set to false

Getting credentials for assume role using cross-account role (best practice)

1. Create role (see Role-Based Authorization)

2. Add the appropriate permission to the role you are using:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": "sts:AssumeRole",
            "Resource": "arn:aws:iam::{Account}:role/{RoleNameWithPath}"
        },
        {
            "Effect": "Allow",
            "Action": [
                "theSameAsIAMPolicyForZabbix",
            ],
            "Resource": "*"
        }
    ]
}

3. Add the principal to the trust relationships of the role you are using:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "AWS": "arn:aws:iam::{Account}:role/{RoleNameWithPath}"
      },
      "Action": "sts:AssumeRole"
    }
  ]
}

⚠ Using assume role with role-based authorization is only possible when you use a Zabbix server or proxy inside AWS.

4. Test it

Connect to ES2 ssh terminal in the instance and run:

  • Go to EC2 → Instances → Select an instance → Connect → SSH client

Get assume role credentials using role name from instance metadata service:

aws sts assume-role --role-arn arn:aws:iam::123456789010:role/NewRole --role-session-name test-session

An example of response:

{
    "Credentials": {
        "AccessKeyId": "ACCESS_KEY_ID",
        "SecretAccessKey": "SECRET_ACCESS_KEY",
        "SessionToken": "SESSION_TOKEN",
        "Expiration": "EXPIRATION_DATE"
    },
    "AssumedRoleUser": {
        "AssumedRoleId": "ASSUMED_ROLE_ID",
        "Arn": "arn:aws:sts::ACCOUNT_ID:assumed-role/ROLE_NAME/SESSION_NAME"
    }
}

5. Set the following macros in Zabbix:

  • {$AWS.AUTH_TYPE} – set to assume_role
  • {$AWS.ASSUME.ROLE.ARN} – set to your role ARN
  • {$AWS.ASSUME.ROLE.AUTH.METADATA} – set to true

Well done! You have successfully configured AWS authorization in Zabbix AWS templates.

Now you can use the template to collect metrics from AWS.

The post Understanding HTTP Template Authorization in AWS appeared first on Zabbix Blog.

Transforming IT Infrastructure Visibility at Doğan Trend Automotive

Post Syndicated from Michael Kammer original https://blog.zabbix.com/transforming-it-infrastructure-visibility-at-dogan-trend-automotive/30715/

Established in 2020 to consolidate Doğan Group’s automotive and mobility companies and brands under a single entity, Doğan Trend Automotive is a prominent player in their industry. Representing a diverse portfolio ranging from automobiles, motorcycles, and marine engines to electric commercial vehicles, Doğan Trend also delivers innovative solutions to customers through its e-commerce platforms, such as suvmarket.com and vespastoreturkey.com.

The challenge

Doğan Trend’s IT ecosystem spans data centers, remote locations, and multiple units, necessitating seamless operations as well as an efficient monitoring and alert system. The existing infrastructure posed challenges in monitoring, making it difficult to detect potential issues in a timely manner, thus increasing operational risks.

The solution

To address Doğan Trend’s needs, our associates at ASNSKY implemented a Zabbix-based monitoring system. Key highlights of the project included:

  • Centralized dashboards: Custom dashboards were designed for data centers and remote locations, enabling the unified monitoring of IT locations and components from a single interface.
  • A dynamic alert system: Alerts prioritized based on predefined conditions allowed for the swift and effective resolution of critical issues.
  • Seamless operations: Early detection of potential issues prevented operational disruptions and ensured continuity.

Throughout the integration process, ASNSKY’s team collaborated closely with Doğan Trend’s IT department, addressing the specific requirements of different units and providing training for effective system use.

The results

Implementing the new monitoring system rapidly delivered the following results:

  • Enhanced visibility: Real-time monitoring of all IT locations and components made potential issues easy to spot.
  • Proactive issue management: Early detection of critical issues reduced operational downtime.
  • Increased efficiency: The centralized monitoring system drastically improved the responsiveness and effectiveness of Doğan Trend’s IT team.

“This project with the ASNSKY team made our IT infrastructure more transparent and manageable. With Zabbix’s flexible and effective monitoring capabilities, we gained active control over our critical operations. We thank the ASNSKY team for this successful collaboration.” – Burak Altunalan, IT System Management Specialist at Doğan Trend Automotive

In conclusion

Doğan Trend plans to further take advantage of Zabbix’s flexibility to strengthen their resilience and operational efficiency. Their association with ASNSKY marks a significant step toward achieving these objectives.

To learn more about what Zabbix can do for retail customers in every sector, get in touch with us. 

About ASNSKY

ASNSKY enhances its customers’ competitiveness by integrating the power of enterprise-grade open-source-solutions in security and infrastructure with a professional service approach and high quality standards.

Backed by deep industry expertise and a team of seasoned professionals, ASNSKY stands as a trusted partner in your digital transformation journey.

The post Transforming IT Infrastructure Visibility at Doğan Trend Automotive appeared first on Zabbix Blog.

How to Install Zabbix on Windows with a Linux Subsystem

Post Syndicated from Alexander Petrov-Gavrilov original https://blog.zabbix.com/how-to-install-zabbix-on-windows-with-a-linux-subsystem/30311/

It’s a very well known fact that Zabbix can only be installed on Linux. But what if you are in a Windows environment and getting a Linux machine is not so simple or even possible? This can obstruct the implementation of Zabbix, or at least significantly delay it. Not only that, building a POC outside of the future environment makes data procurement a lot more complicated. Is there a way to work around this and get Zabbix as close to Windows as we possibly can?

WSL

WSL/WSL 2 is a fast and easy solution for installing and using Zabbix in a smaller Windows-dominant environment, be that a POC or a small company office. WSL 2 runs a real Linux kernel in a lightweight VM while being optimized for Windows. This means a faster start, lower resource consumption, and the ability to share files with Windows directly, meaning you can use Windows File explorer to find and manage the VM files.

WSL 2 also allows you to use Linux CLI while working with Windows (i.e. running vim from a Windows terminal and editing Windows files directly). At this point, you may be asking yourself, “Why not Hyper-V and VirtualBox?” Those are definitely options too, but they are quite heavy on system resources. In addition, boot times are a bit longer and sharing files between a host and a guest OS is clunkier.

Maybe Docker Desktop then? It’s an absolutely valid option, but that would require a bit of Docker knowledge and you would still be using WSL, technically speaking. So, with that said, WSL is definitely the fastest and most reliable way to sprung a Zabbix instance in a Windows-focused environment.

We will use WSL 2, but as a note WSL 1 is also available. Here are the differences:

  • WSL 2 is usually the better performer overall, especially for dev environments. It also has better Linux compatibility.
  • WSL 1 Linux files aren’t isolated, which can make them more accessible. In WSL 2, Linux runs in a virtual disk (ext4), so Linux and Windows files are more separate. Integration is still pretty good, however.
  • WSL 2 has better Linux compatibility – systemd, iptables, etc.
  • WSL 1 shared the same IP as Windows, WSL 2 is a VM – some networking required.
  • With WSL 1 you can see Linux running processes in Task Manager. WSL 2 will have processes isolated.

Installing Zabbix using WSL

Install WSL

Open PowerShell as an Administrator and run:

PS C:\Windows\system32> wsl --install

If you’ve already have WSL 1 installed, update it:

PS C:\Windows\system32> wsl --update

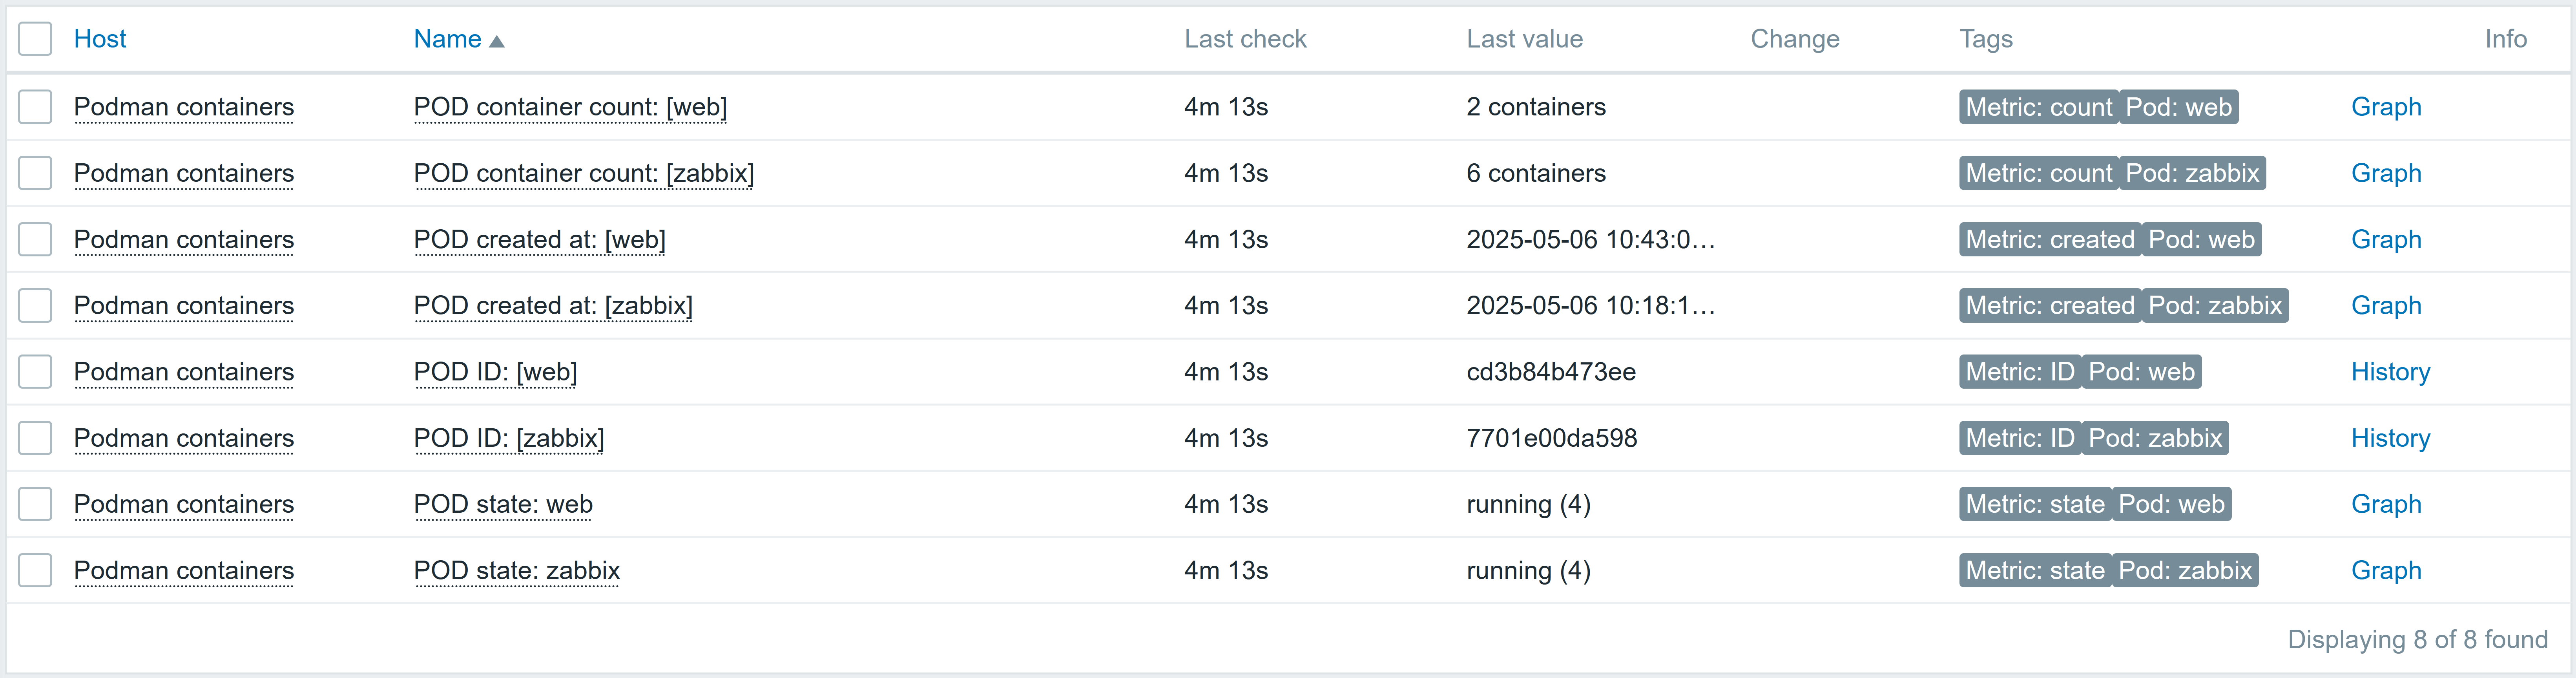
You can also set WSL 2 as default:

PS C:\Windows\system32> wsl --set-default-version 2
WSL installation
WSL installation


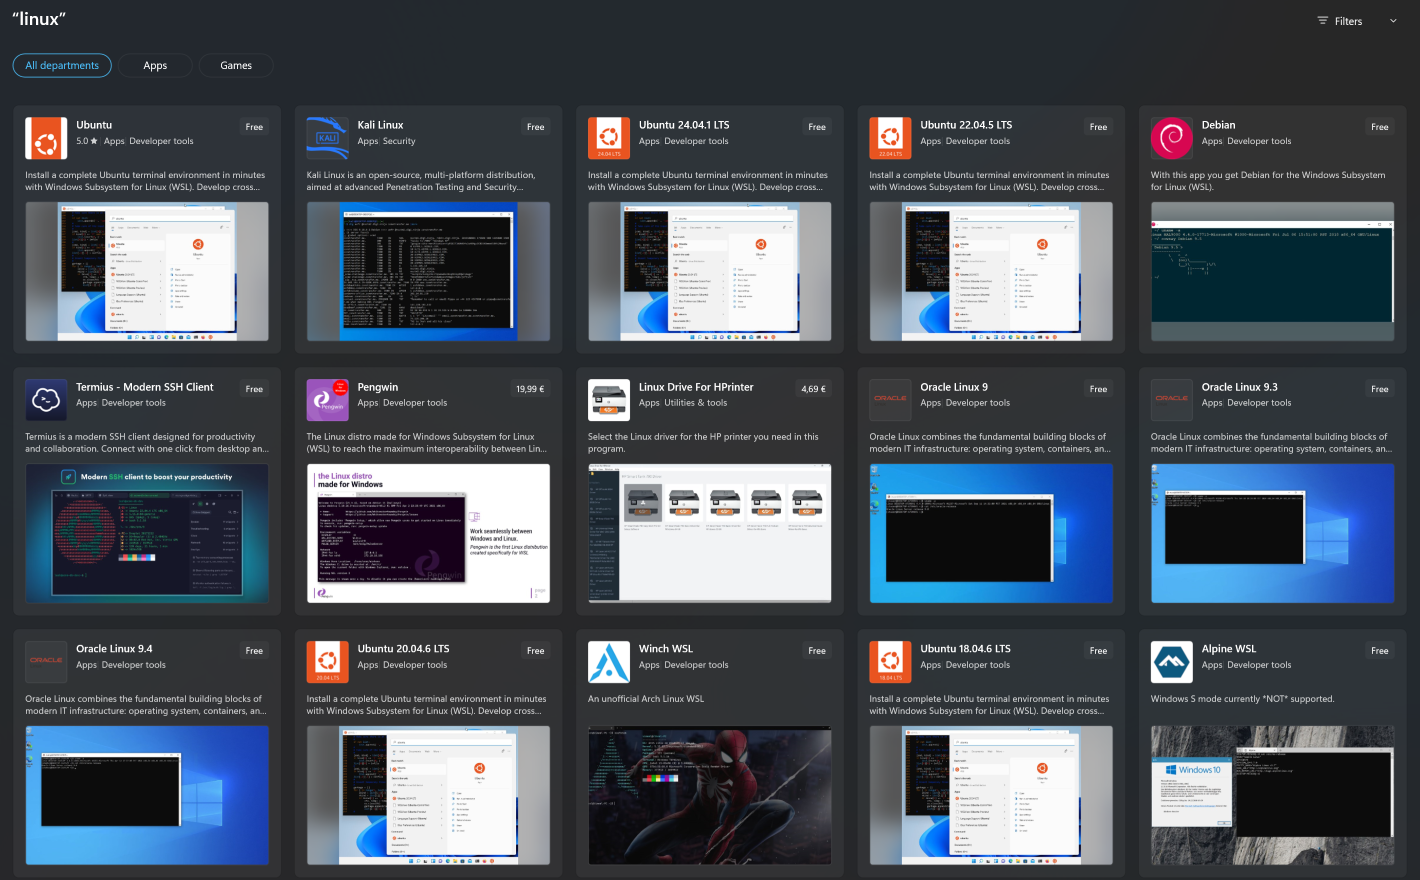
Install/Get preferred Linux Distribution using either Microsoft Store (i.e. Ubuntu, Debian, Oracle Linux) or just download directly. I will be using Oracle Linux 9.4.

Microsoft store WSL images


You can also download the RootFS tarball from the preferred distribution portal, but then the process will be a bit different. Create a folder using PowerShell:

PS C:\Windows\system32> mkdir C:\WSL\OracleLinux9

Copy the .tar.xz file to this folder, then run:

PS C:\Windows\system32> wsl --import OracleLinux9 C:\WSL\OracleLinux9 .\oraclelinux9-rootfs.tar.xz --version 2

After the image is installed or imported, start Oracle Linux using PowerShell:

PS C:\Windows\system32> oraclelinux94

When installation is finished, there is a prompt to create a default UNIX user account and password for the said user, as the username does not need to match your Windows username. I’ll set it to “zabbix” of course, but you can set it to any other.

PS C:\Windows\system32> Enter new UNIX username: 
PS C:\Windows\system32> zabbix
PS C:\Windows\system32> New password: <your-password>
PS C:\Windows\system32> passwd: all authentication tokens updated successfully.
PS C:\Windows\system32> Installation successful!

Now OracleLinux is ready for use!

Prepare the system

You will be immediately logged in to the new environment. If logged out, to log in again just execute in PowerShel:

PS C:\Windows\system32> oraclelinux94

Being logged in, first double check that your selected OS is indeed installed by executing in the PowerShell, which will now serve as your VM CLI access point:

[zabbix@PC-NAME ~]$ cat /etc/os-release
NAME="Oracle Linux Server"
VERSION="9.4"
ID="ol"
ID_LIKE="fedora"
VARIANT="Server"
VARIANT_ID="server"
VERSION_ID="9.4"
PLATFORM_ID="platform:el9"
PRETTY_NAME="Oracle Linux Server 9.4"
ANSI_COLOR="0;31"
CPE_NAME="cpe:/o:oracle:linux:9:4:server"
HOME_URL="https://linux.oracle.com/"
BUG_REPORT_URL=https://github.com/oracle/oracle-linux

Confirmation received, make sure all OS updates are installed:

[zabbix@PC-NAME ~]$ sudo dnf update -y

When the update process is finished, you will need to decide whether you would like to use systemd or not (this may increase booting time). I will enable systemd. To do this, edit the wsl.conf on the Linux subsystem:

vi /etc/wsl.conf

Add to the newly created file:

[boot]
systemd=true

Reboot the images (this command will reboot all of them):

PS C:\Windows\system32> wsl.exe --shutdown

Start back your Linux distribution:

PS C:\Windows\system32> oraclelinux94

Install Zabbix database

We will need to prepare the database engine. Again, any preferred database engine can be used, in this case I install and configure MariaDB:

[zabbix@PC-NAME ~]$ sudo dnf install -y mariadb-server mariadb
[zabbix@PC-NAME ~]$ sudo systemctl enable --now mariadb

Confirm MariaDB is running:

[zabbix@PC-NAME ~]$ Systemctl status mariadb

mariadb.service - MariaDB 10.5 database server
     Loaded: loaded (/usr/lib/systemd/system/mariadb.service; enabled; preset: disabled)
     Active: active (running) since Tue 2025-04-29 12:39:54 EEST; 3min 55s ago
       Docs: man:mariadbd(8)
             https://mariadb.com/kb/en/library/systemd/
   Main PID: 235 (mariadbd)
     Status: "Taking your SQL requests now..."
      Tasks: 9 (limit: 26213)
     Memory: 109.6M
     CGroup: /system.slice/mariadb.service
             └─235 /usr/libexec/mariadbd --basedir=/usr

After confirmation, secure it a bit by creating a root password and selecting the options in bold:

[zabbix@PC-NAME ~]$ sudo mysql_secure_installation 

Enter current password for root (enter for none):
OK, successfully used password, moving on...

Setting the root password or using the unix_socket ensures that nobody
can log into the MariaDB root user without the proper authorisation.

You already have your root account protected, so you can safely answer 'n'.

Switch to unix_socket authentication [Y/n] n
 ... skipping.

You already have your root account protected, so you can safely answer 'n'.

Change the root password? [Y/n] Y
New password:
Re-enter new password:
Password updated successfully!
Reloading privilege tables..
 ... Success!

Remove anonymous users? [Y/n] Y
 ... Success!

Disallow root login remotely? [Y/n] Y
 ... Success!

Remove test database and access to it? [Y/n] Y


Reload privilege tables now? [Y/n] Y

 ... Success!

Cleaning up...

All done!  If you've completed all of the above steps, your MariaDB
installation should now be secure.

Thanks for using MariaDB!

Now to create the Zabbix database. Log in to MariaDB:

[zabbix@PC-NAME ~]$ sudo mysql -u root -p 
[zabbix@PC-NAME ~]$ Enter password: <enter your password, won’t be visible>

Follow the steps from the Zabbix installation page:

MariaDB [(none)]> create database zabbix character set utf8mb4 collate utf8mb4_bin;
MariaDB [(none)]> create user zabbix@localhost identified by '<custom-password>';
MariaDB [(none)]> grant all privileges on zabbix.* to zabbix@localhost;
MariaDB [(none)]> set global log_bin_trust_function_creators = 1;

MariaDB [(none)]> quit;

Installing Zabbix

Install the Zabbix repository:

[zabbix@PC-NAME ~]$ sudo dnf install https://repo.zabbix.com/zabbix/7.0/centos/9/x86_64/zabbix-release-latest-7.0.el9.noarch.rpm
[zabbix@PC-NAME ~]$ dnf clean all

Proceed to install the Zabbix server, frontend, and agent:

[zabbix@PC-NAME ~]$ sudo dnf -y install zabbix-server-mysql zabbix-web-mysql zabbix-apache-conf zabbix-sql-scripts zabbix-selinux-policy zabbix-agent
...
[zabbix@PC-NAME ~]$zabbix-agent-7.0.12-release1.el9.x86_64 zabbix-apache-conf-7.0.12-release1.el9.noarch zabbix-selinux-policy-7.0.12-release1.el9.x86_64  zabbix-server-mysql-7.0.12-release1.el9.x86_64 zabbix-sql-scripts-7.0.12-release1.el9.noarch
 zabbix-web-7.0.12-release1.el9.noarch zabbix-web-deps-7.0.12-release1.el9.noarch zabbix-web-mysql-7.0.12-release1.el9.noarch

Complete!

Now import the initial database schema:

[zabbix@PC-NAME ~]$ zcat /usr/share/zabbix-sql-scripts/mysql/server.sql.gz | mysql -u zabbix -p zabbix
Enter password: <enter your DB user password and wait until you will see the next line appear>
[root@ZBX-5CD3221K14 zabbix]#

Disable the log_bin_trust_function_creators option after import has finished:

# mysql -uroot -p
password
MariaDB [(none)]>  set global log_bin_trust_function_creators = 0;
MariaDB [(none)]>  quit;

Add your Zabbix user database password to the Zabbix server configuration file:

[zabbix@PC-NAME ~]$ vi /etc/zabbix/zabbix_server.conf
### Option: DBPassword
#       Database password.
#       Comment this line if no password is used.
#
# Mandatory: no
# Default:
DBPassword=<your-DB-user-password>

Start the Zabbix server and frontend and add them to autorun:

[zabbix@PC-NAME ~]$  systemctl restart zabbix-server zabbix-agent httpd php-fpm
[zabbix@PC-NAME ~]$  systemctl enable zabbix-server zabbix-agent httpd php-fpm
Created symlink /etc/systemd/system/multi-user.target.wants/zabbix-server.service → /usr/lib/systemd/system/zabbix-server.service.
Created symlink /etc/systemd/system/multi-user.target.wants/zabbix-agent.service → /usr/lib/systemd/system/zabbix-agent.service.
Created symlink /etc/systemd/system/multi-user.target.wants/httpd.service → /usr/lib/systemd/system/httpd.service.
Created symlink /etc/systemd/system/multi-user.target.wants/php-fpm.service → /usr/lib/systemd/system/php-fpm.service.

Installation of the backend is now finished, but we still need the frontend.

Exposing and installing the Zabbix frontend for WSL

Since WSL2 does not expose services to localhost by default, you need to determine the WSL IP:

[zabbix@PC-NAME ~]$ ip addr show eth0
2: eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc mq state UP group default qlen 1000
    link/ether 00:15:5d:47:32:c6 brd ff:ff:ff:ff:ff:ff
    inet 172.29.128.155/20 brd 172.29.143.255 scope global eth0
       valid_lft forever preferred_lft forever
    inet6 fe80::215:5dff:fe47:32c6/64 scope link
       valid_lft forever preferred_lft forever

Look for an IP like 172.x.x.x, then using your browser go to:

http://<WSL_IP>/zabbix

In this example, that would be: 

http://172.29.128.155/zabbix

You can also port forward WSL to localhost with netsh in PowerShell:

PS C:\Windows\system32> netsh interface portproxy add v4tov4 listenport=8080 listenaddress=127.0.0.1 connectport=80 connectaddress=<WSL_IP>

Then you will be able to access Zabbix from http://localhost:8080/zabbix. Now, just finish the standard frontend setup and Zabbix is ready to use!

WSL advantages

Some extra advantages you get with this approach include clearer resource usage visibility:

WSL Task manager


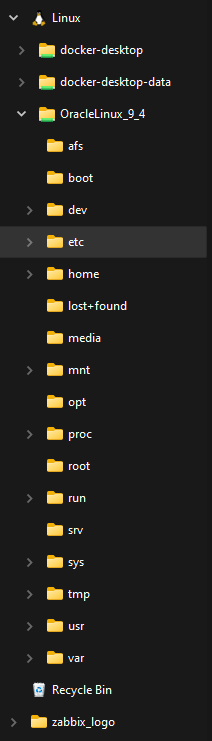
Direct access to the Linux subsystem files through File explorer with your favorite Windows tools:

Linux subsystem file explorer


As you can see, docker is here as well. System and configuration files are also visible and editable:

File explorer Zabbix config files


Now you can proceed with building your Zabbix or Zabbix POC, (almost) without needing to leave your regular Windows environment!

The post How to Install Zabbix on Windows with a Linux Subsystem appeared first on Zabbix Blog.

Zabbix and a Federal Government Agency

Post Syndicated from Michael Kammer original https://blog.zabbix.com/zabbix-and-a-federal-government-agency/30708/

Our Premium Partners at the ATS Group work with a large federal government agency in the United States. They primarily provide storage and compute-as-a-service for the agency, which relies on them to stay up and running at all times.

The challenge

The agency’s primary goal was to simplify their capacity and performance monitoring without extra costs. They had very strict regulatory and SLO oversight requirements that had to be met, especially when it came to capacity and performance.

There was no commercially available software that could accomplish everything they needed directly out of the box, but they still required a solution that was powerful and flexible enough to monitor almost anything.

The solution

Because the agency has several different data centers of different sizes, they use a distributed proxy set up, intense SLA reporting, a ServiceNow integration, a variety of internal integrations, and a monitoring solution provided by Zabbix that includes a predictive alerting setup.

The agency has plenty of software in the mix, but it primarily relies on storage, VMWare, and Kubernetes. They also have multiple satellite offices and data centers, so that in the event of a data center failure, another can come online with minimal downtime in between.

On top of that, they have over 30 metrics and more than a trillion data points across 10 major technologies that they need to measure, primarily from a regulatory perspective. Thousands of granular metrics needed to have solutions and reporting designed for them in Zabbix, including (for example) CPU cores and frequency, processor-to-core usage metrics, and virtualization ratios from hosts to virtual machines.

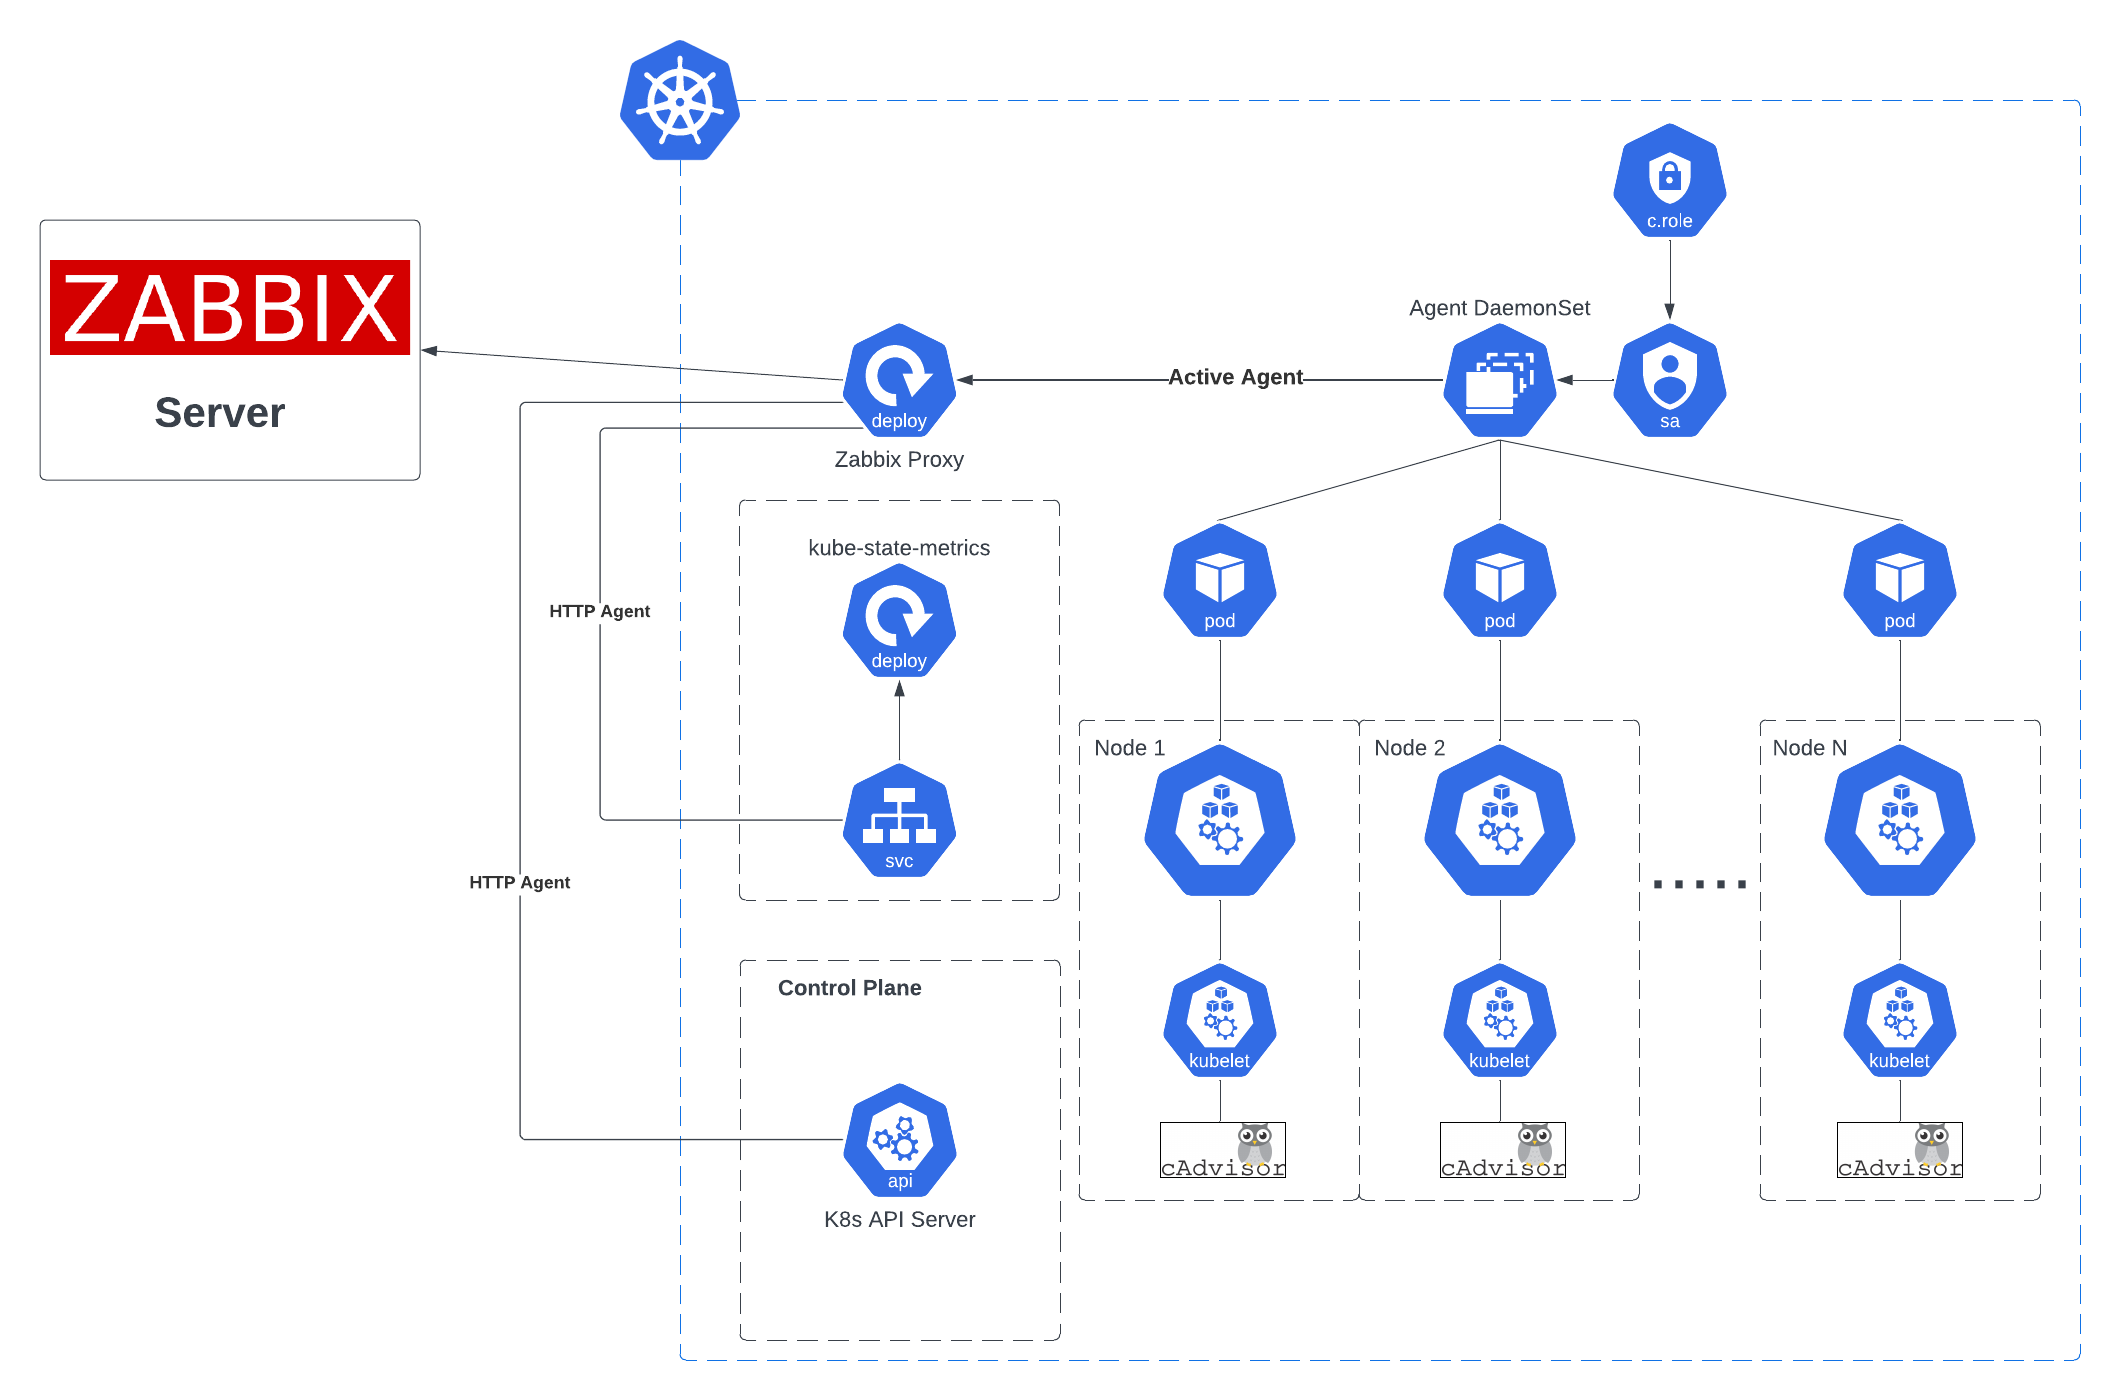
Their Kubernetes-based Openshift environment also needs to be monitored to exact specifications. Deployment took place via Helm Chart, with Zabbix components being installed as Kubernetes resources, node-level resources, and applications being monitored, while data was aggregated and sent to the Zabbix server.

Metrics are collected via the Kubernetes API and kube-state metrics, and the solution uses Prometheus-exported metrics or direct HTTP endpoint calls. When it comes to configuration, proxies and hosts are created in Zabbix to represent Kubernetes nodes and clusters, while templates and macros are configured to point to the Kubernetes API and kube-state-metrics endpoints.

The results

Thanks to Zabbix, the federal government agency in question has a solution that provides centralized monitoring of Kubernetes alongside other IT resources, supports application-specific metrics without requiring Prometheus endpoints, and offers plenty of flexibility to customize and scale.

In addition, Zabbix’s predictive alerting capabilities identify abnormalities in operational data and predictively alert the agency about anything that could potentially impact an application or service, which lets them meet SLAs, optimize user experience, and increase productivity.

In conclusion

Zabbix’s flexibility and ease of customization make it ideal for customers who need a single source of truth that can be relied on in even the most stringent regulatory environments.

To learn more about what Zabbix can do for customers in the public sector, visit us here.

The post Zabbix and a Federal Government Agency appeared first on Zabbix Blog.

Podman Container Monitoring with Prometheus Exporter, part 2

Post Syndicated from Janis Eidaks original https://blog.zabbix.com/podman-container-monitoring-with-prometheus-exporter-part-2/30538/

In the first part of this post, we explored how to get data with HTTP agent from the Prometheus Podman exporter and use the same item data for the Podman pods Discovery rule as well as item and trigger prototypes. In part 2 of the same series, we’ll learn how to discover and monitor Podman containers.

Creating a template discovery rule

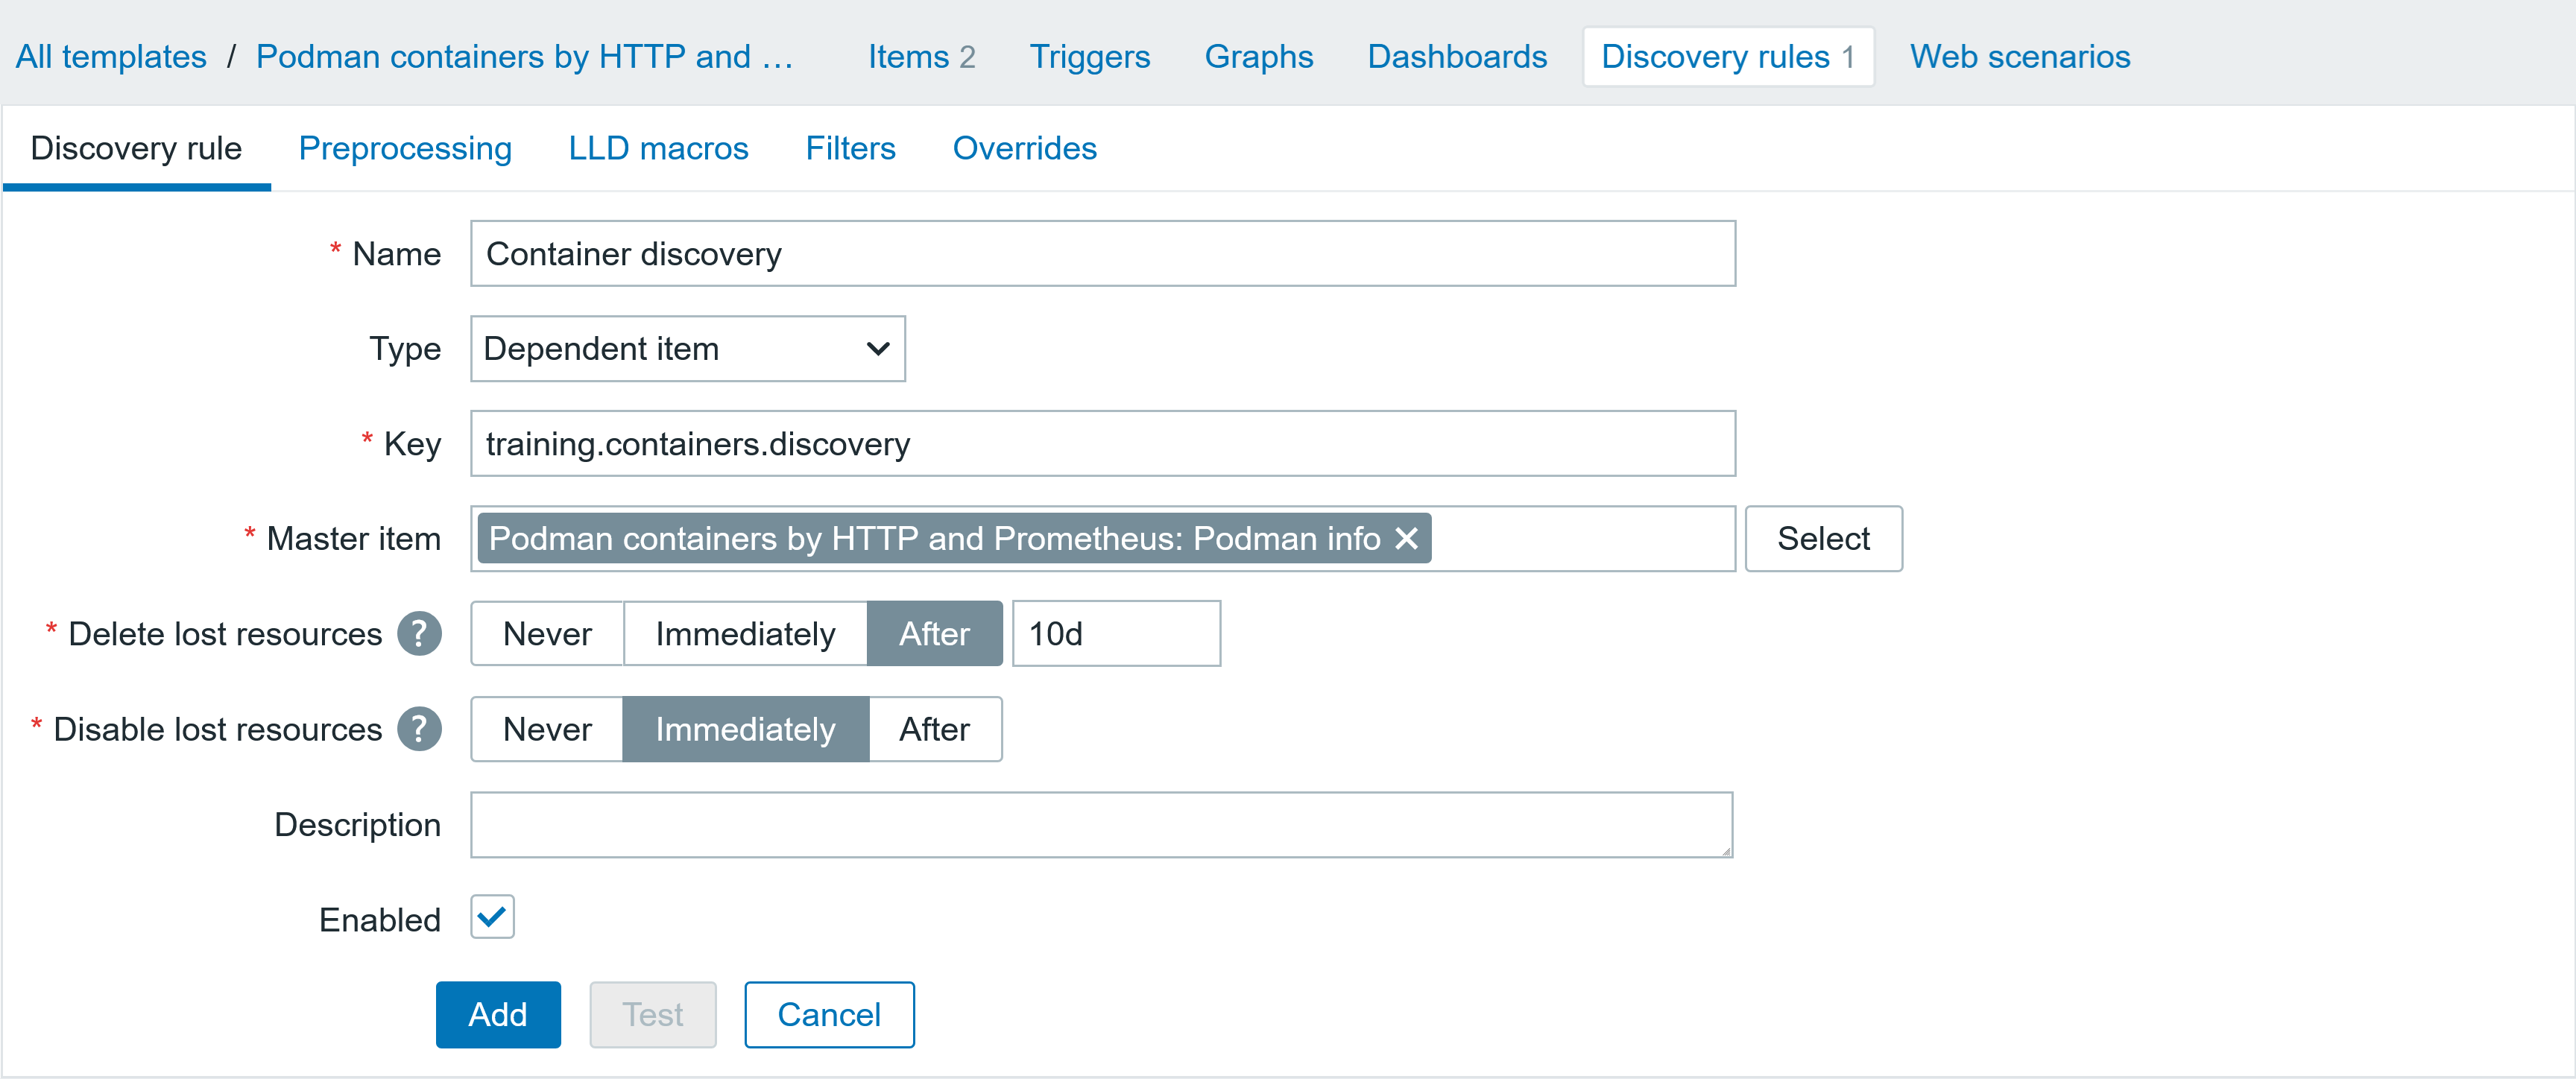
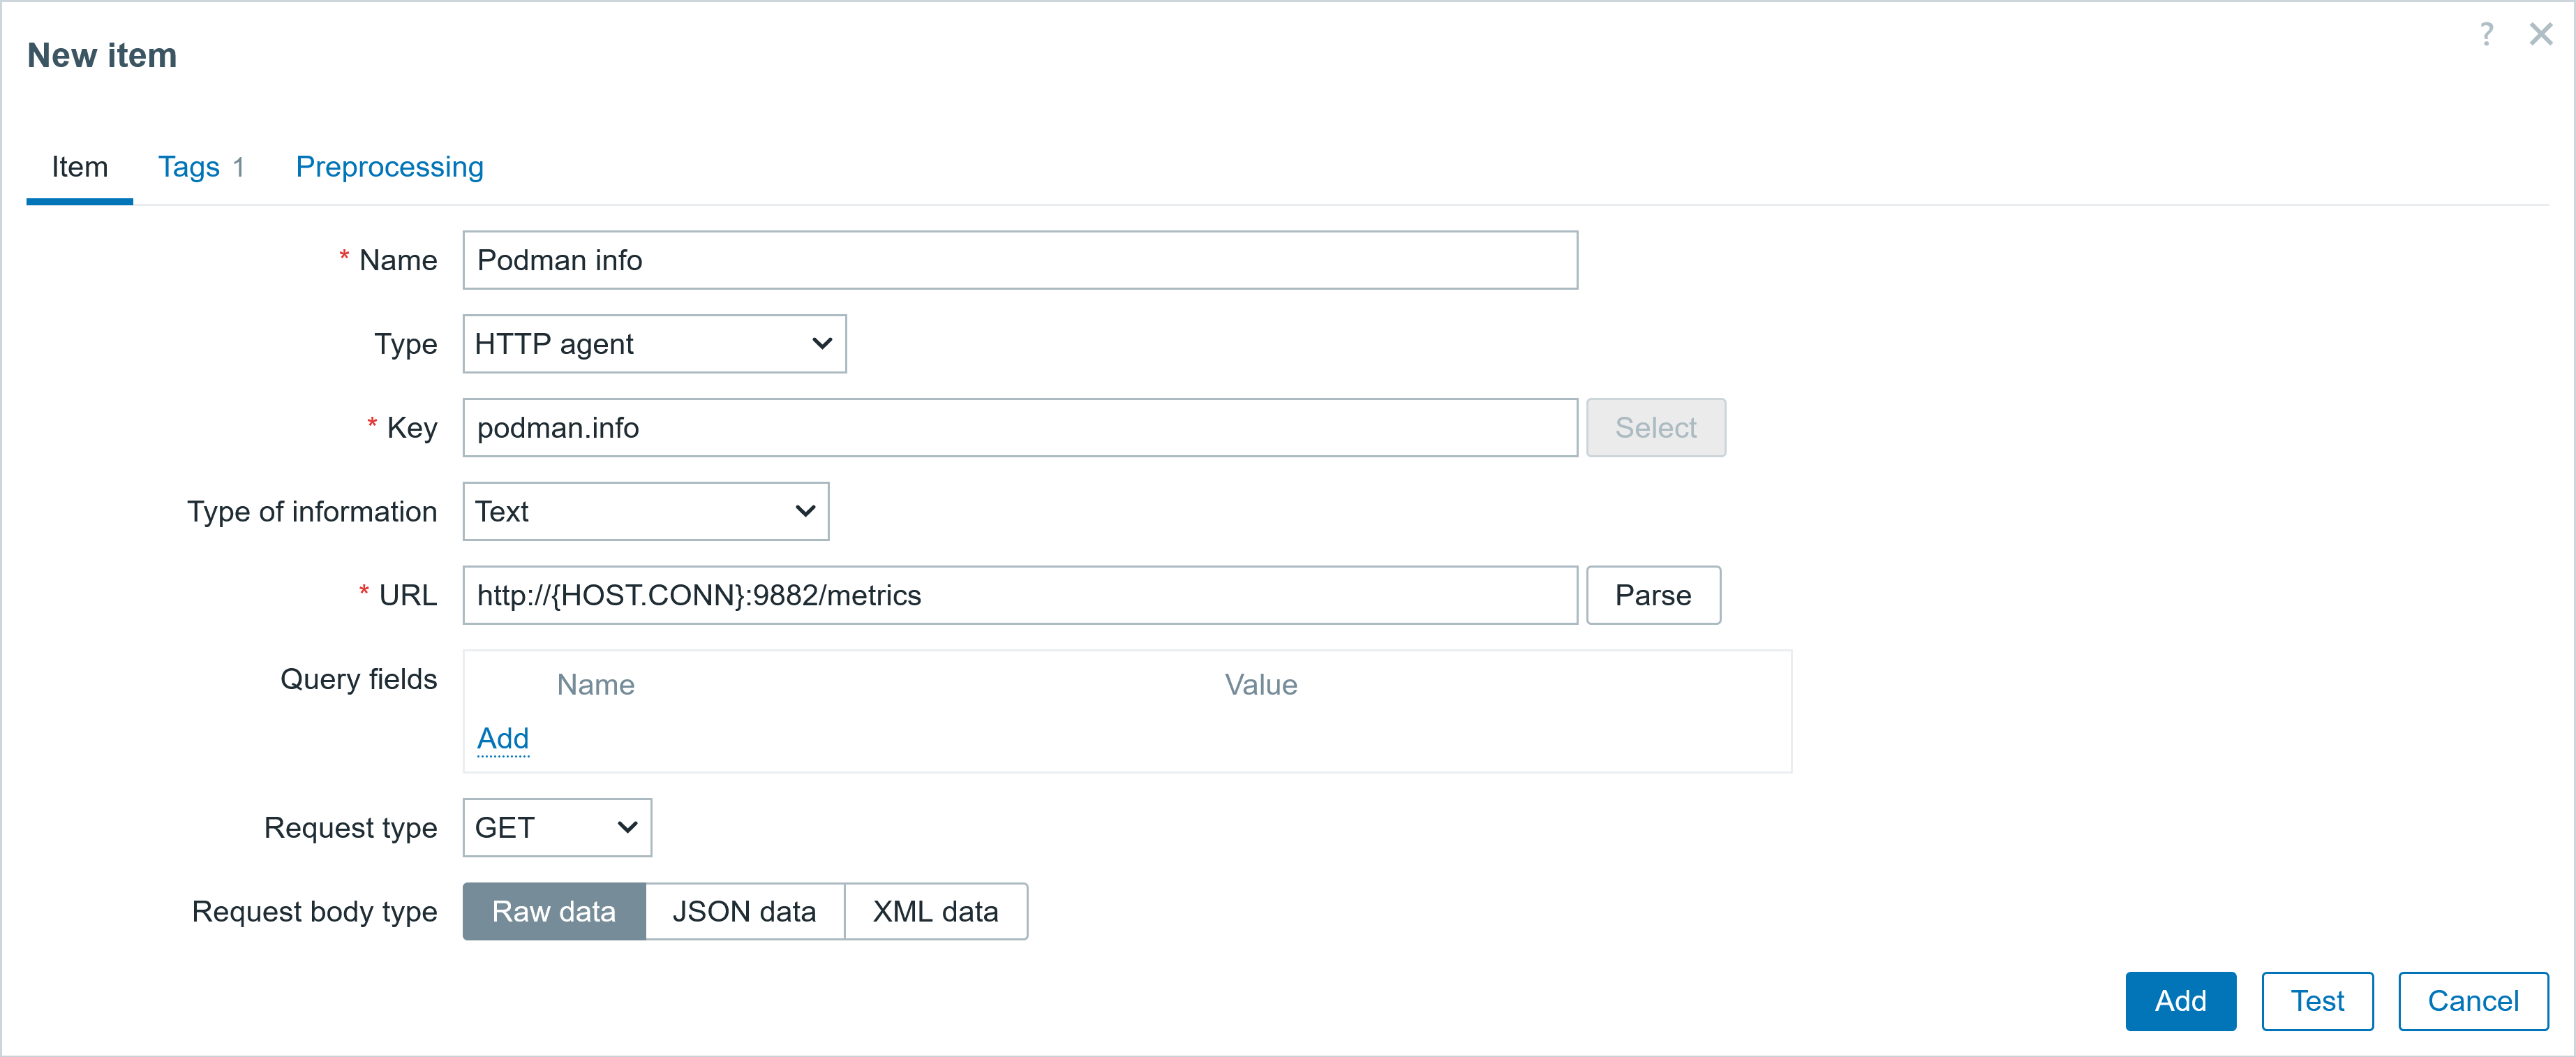
I will create another discovery rule for container discovery. This discovery rule is also based on the same item [Podman info] in the template – Podman containers by HTTP and Prometheus (you can check part one of this series to find out how to configure it). The parameters of the discovery rule are shown below. This discovery rule will allow us to discover the pod name and ID.

Template: Podman containers by HTTP and Prometheus

▲ Discovery rule
  ▪ Name:                   Container discovery
  ▪ Type                    Dependent item
  ▪ Key:                    training.containers.discovery
  ▪ Master item             Podman containers by HTTP and Prometheus: Podman info
  ▪ Delete lost resources  After 10d
  ▪ Disable lost resources Immediately
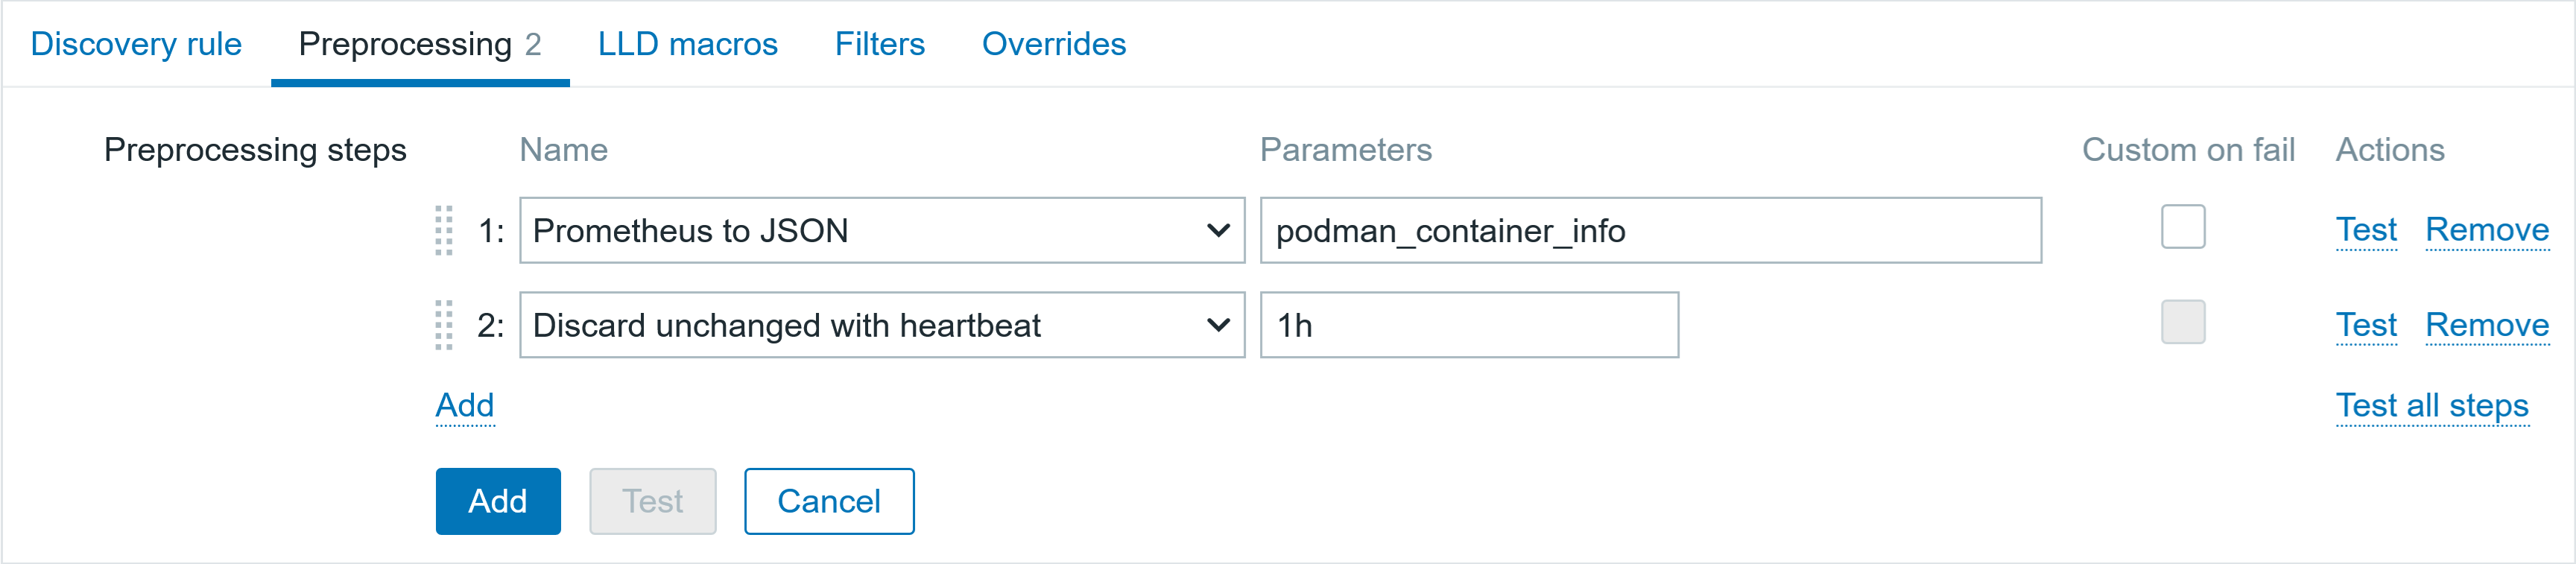
♯ Preprocessing
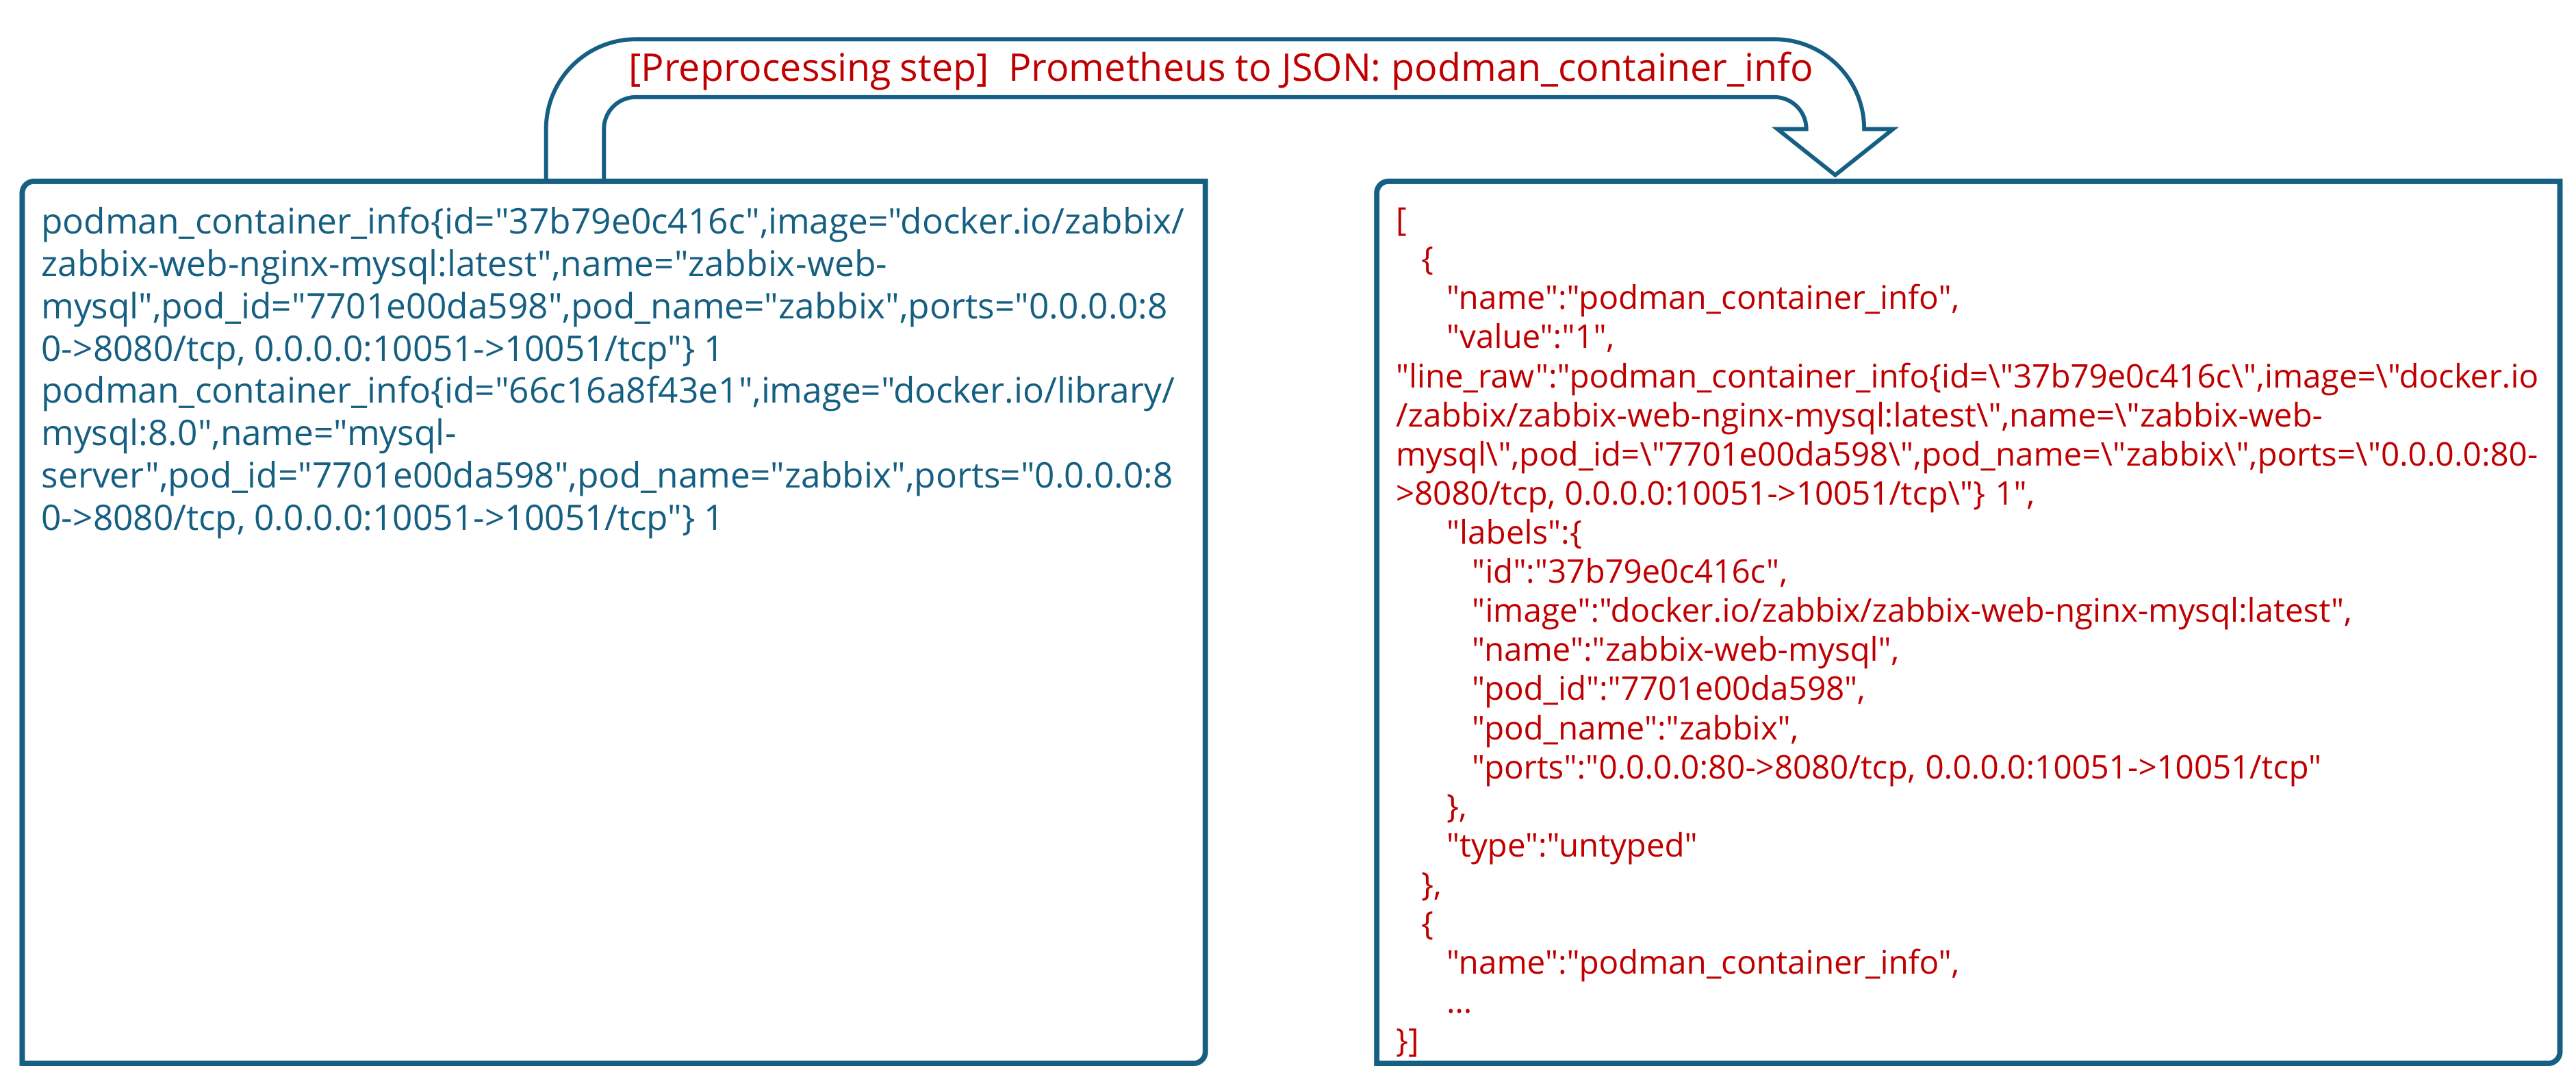
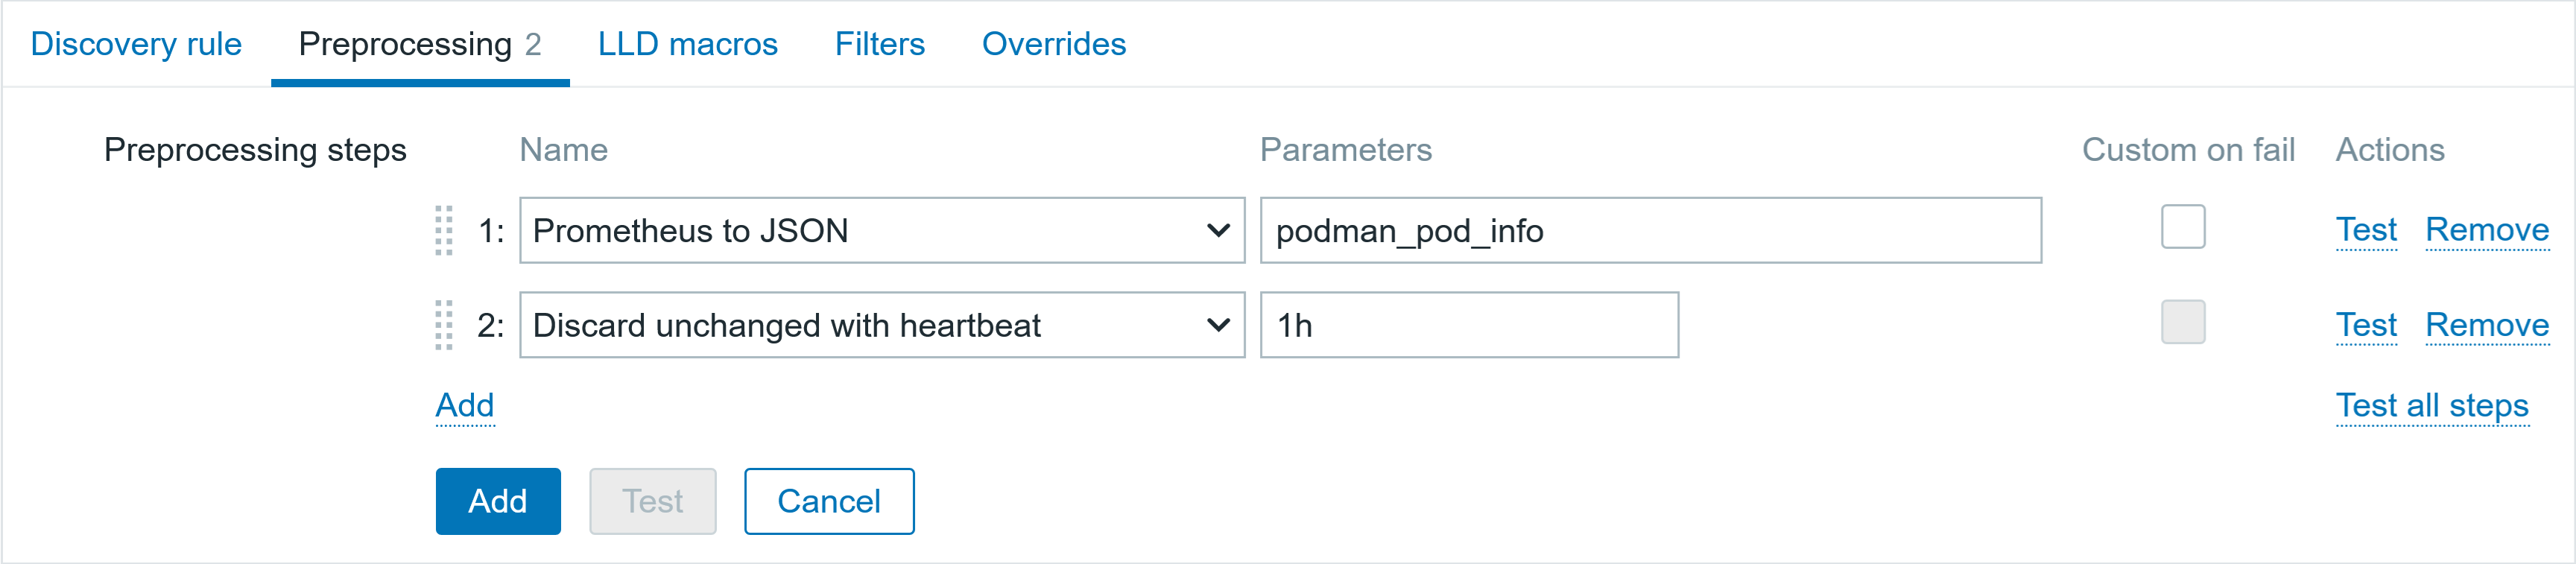
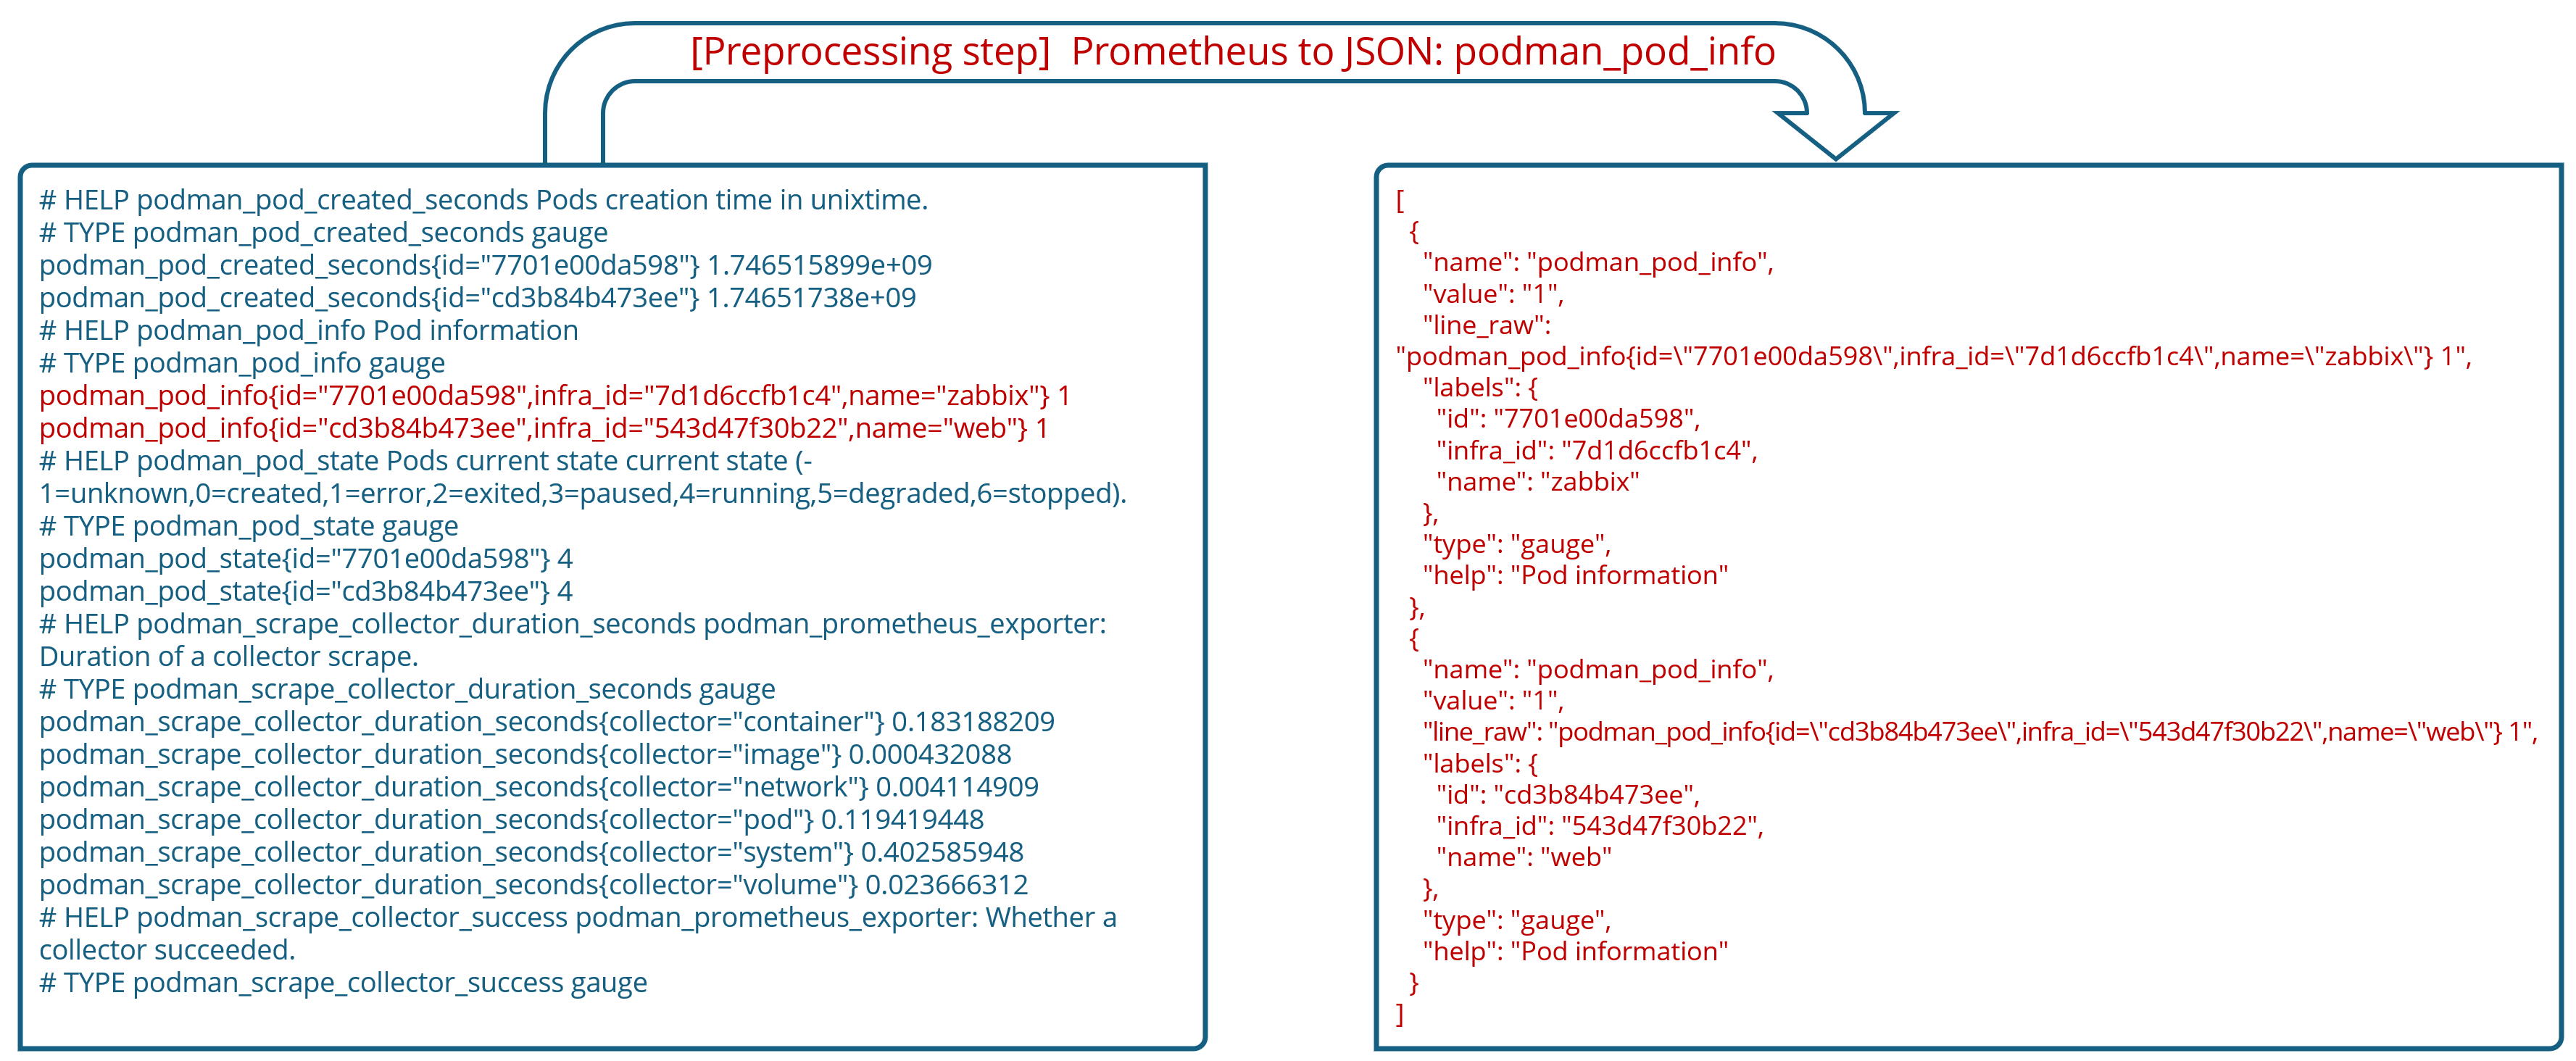
  ▪ Prometheus to JSON     podman_container_info
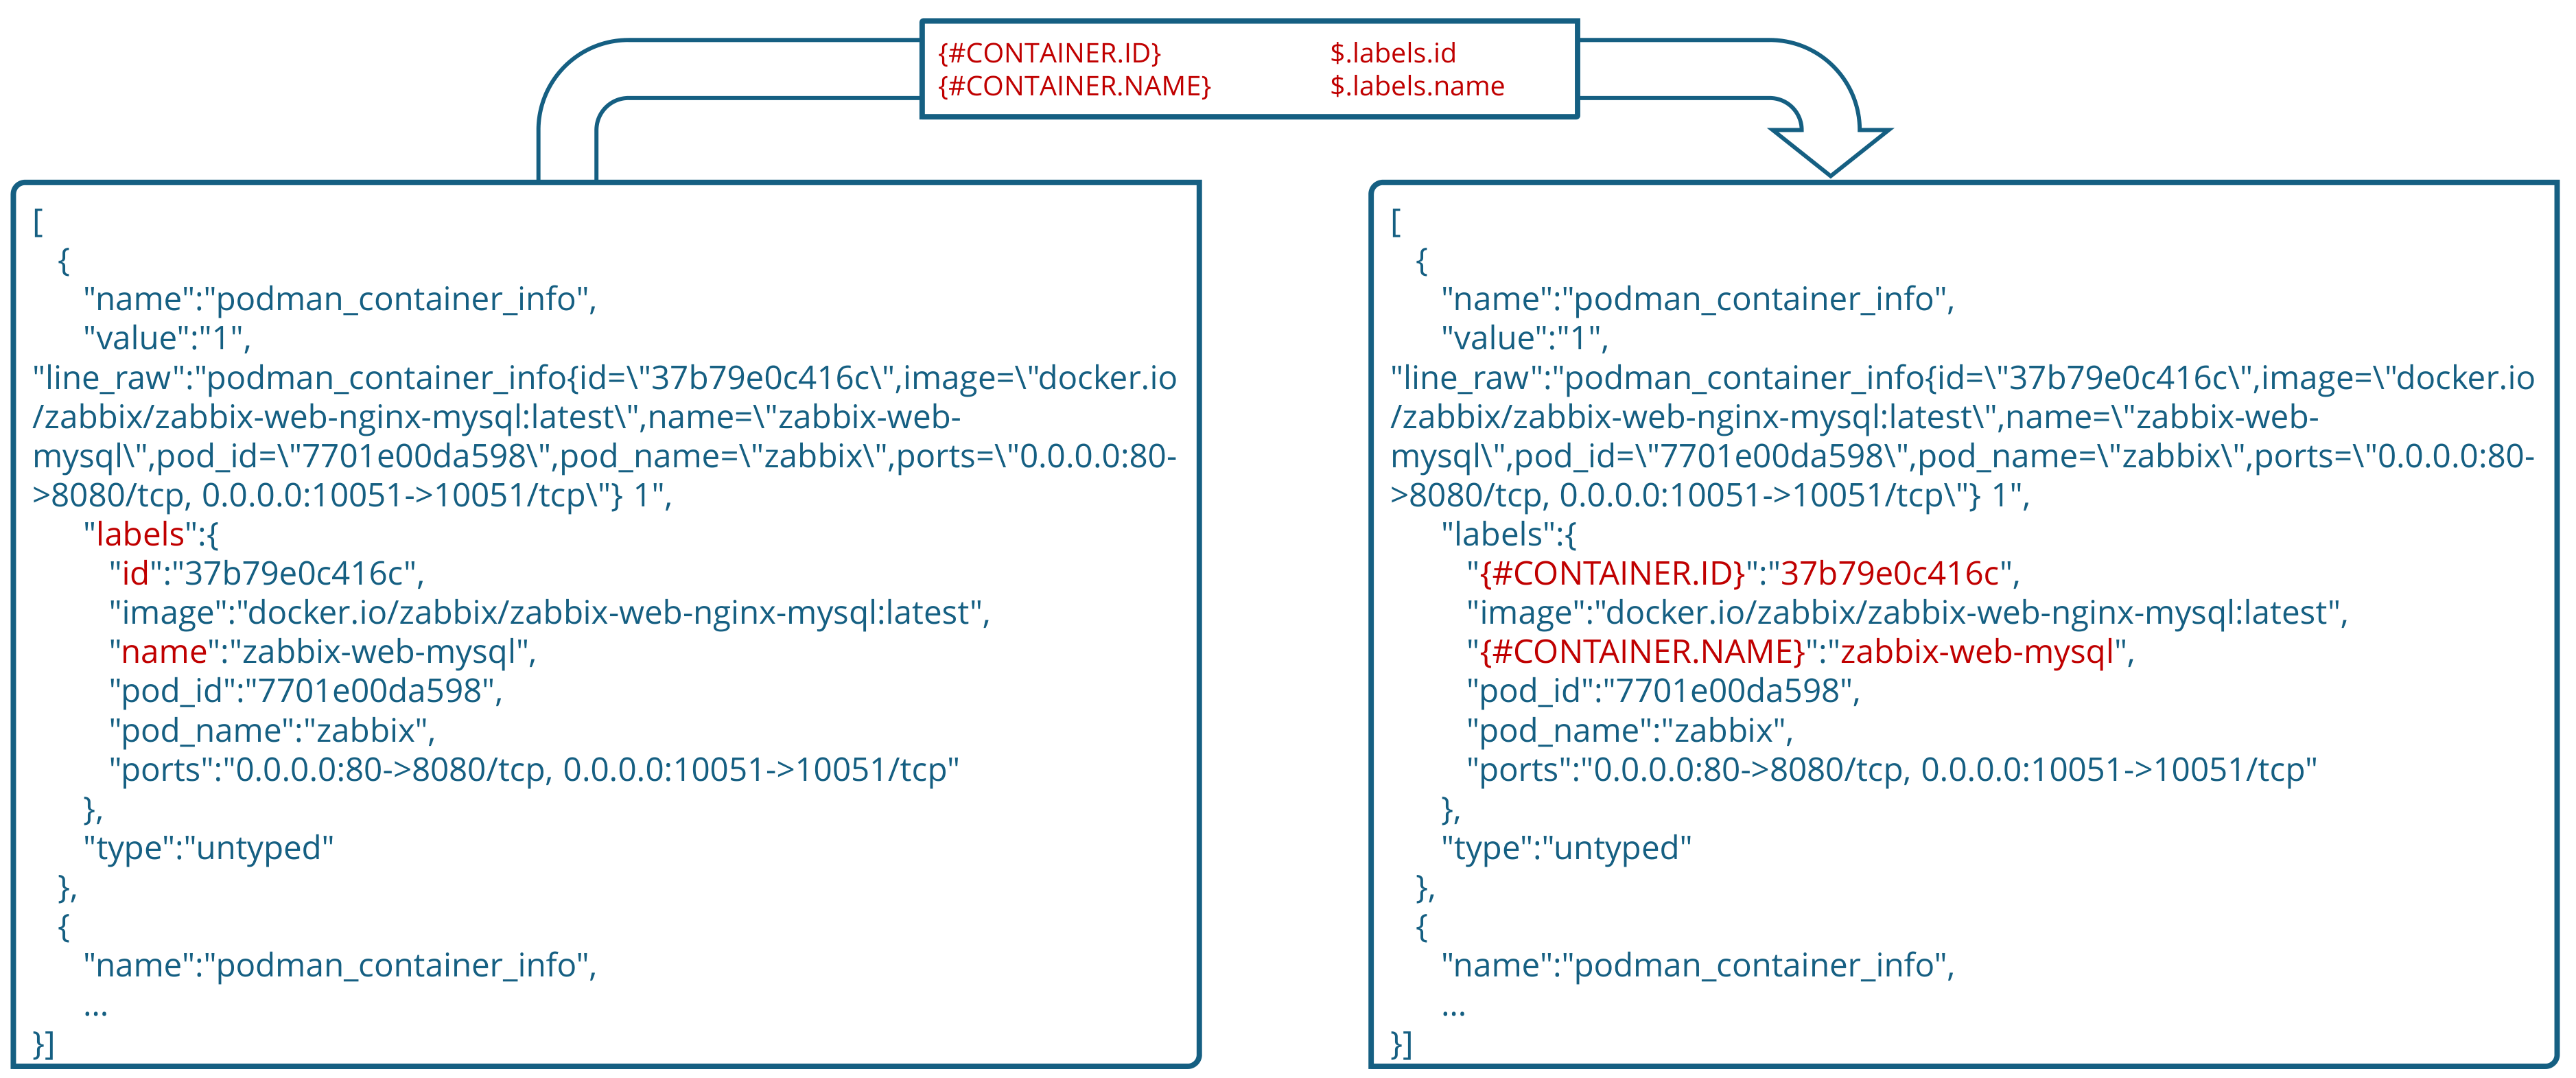
♦ LLD Macros
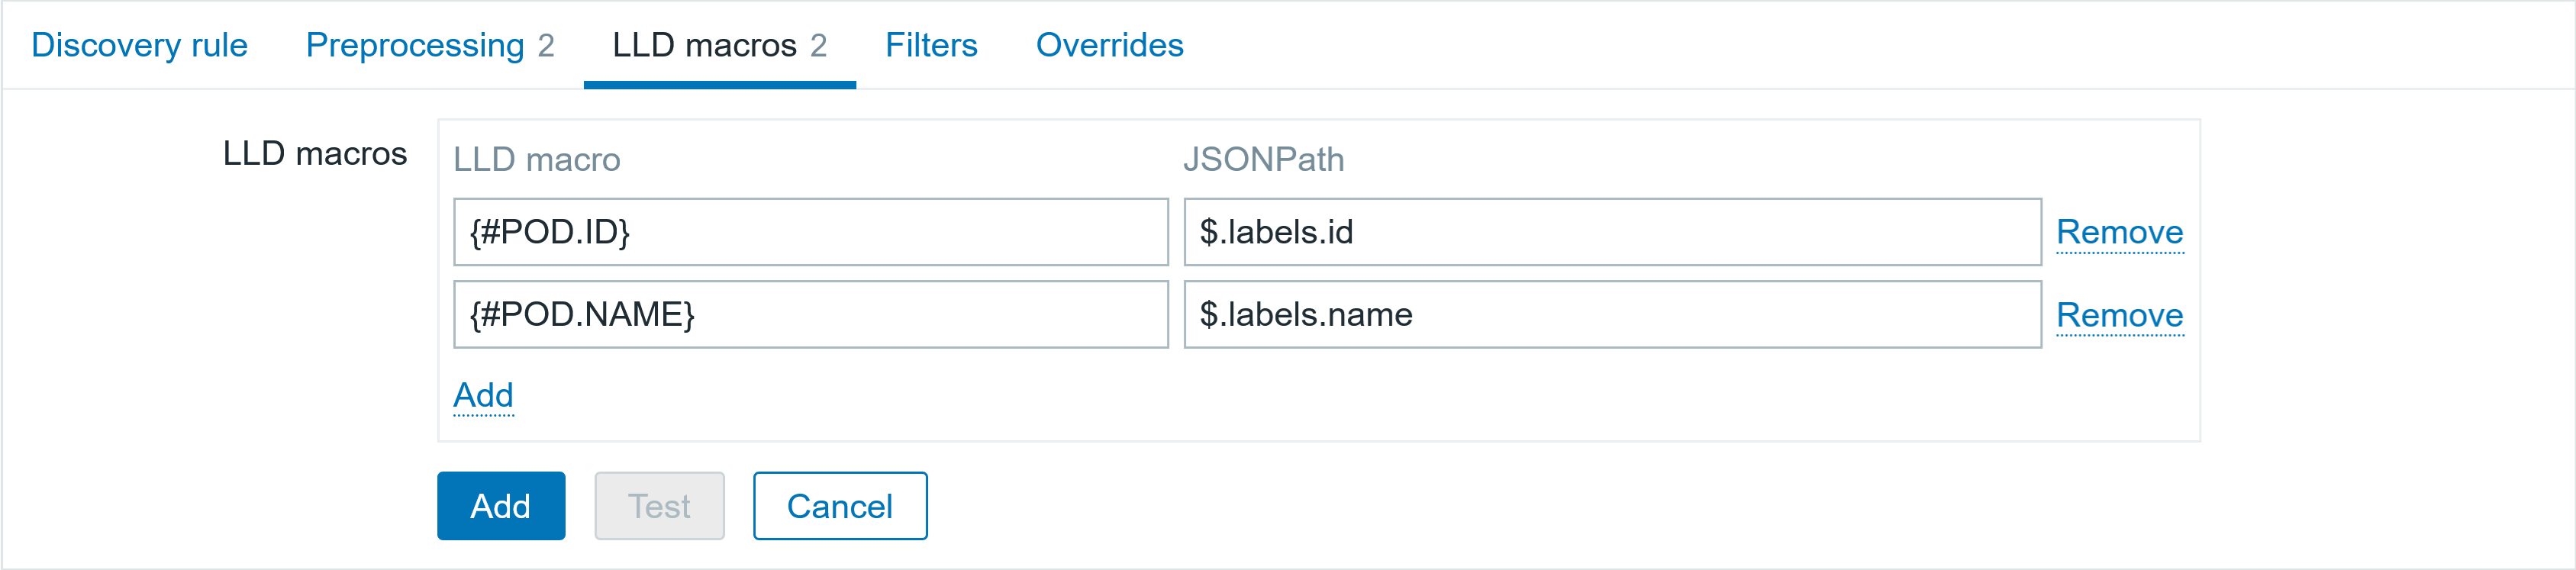
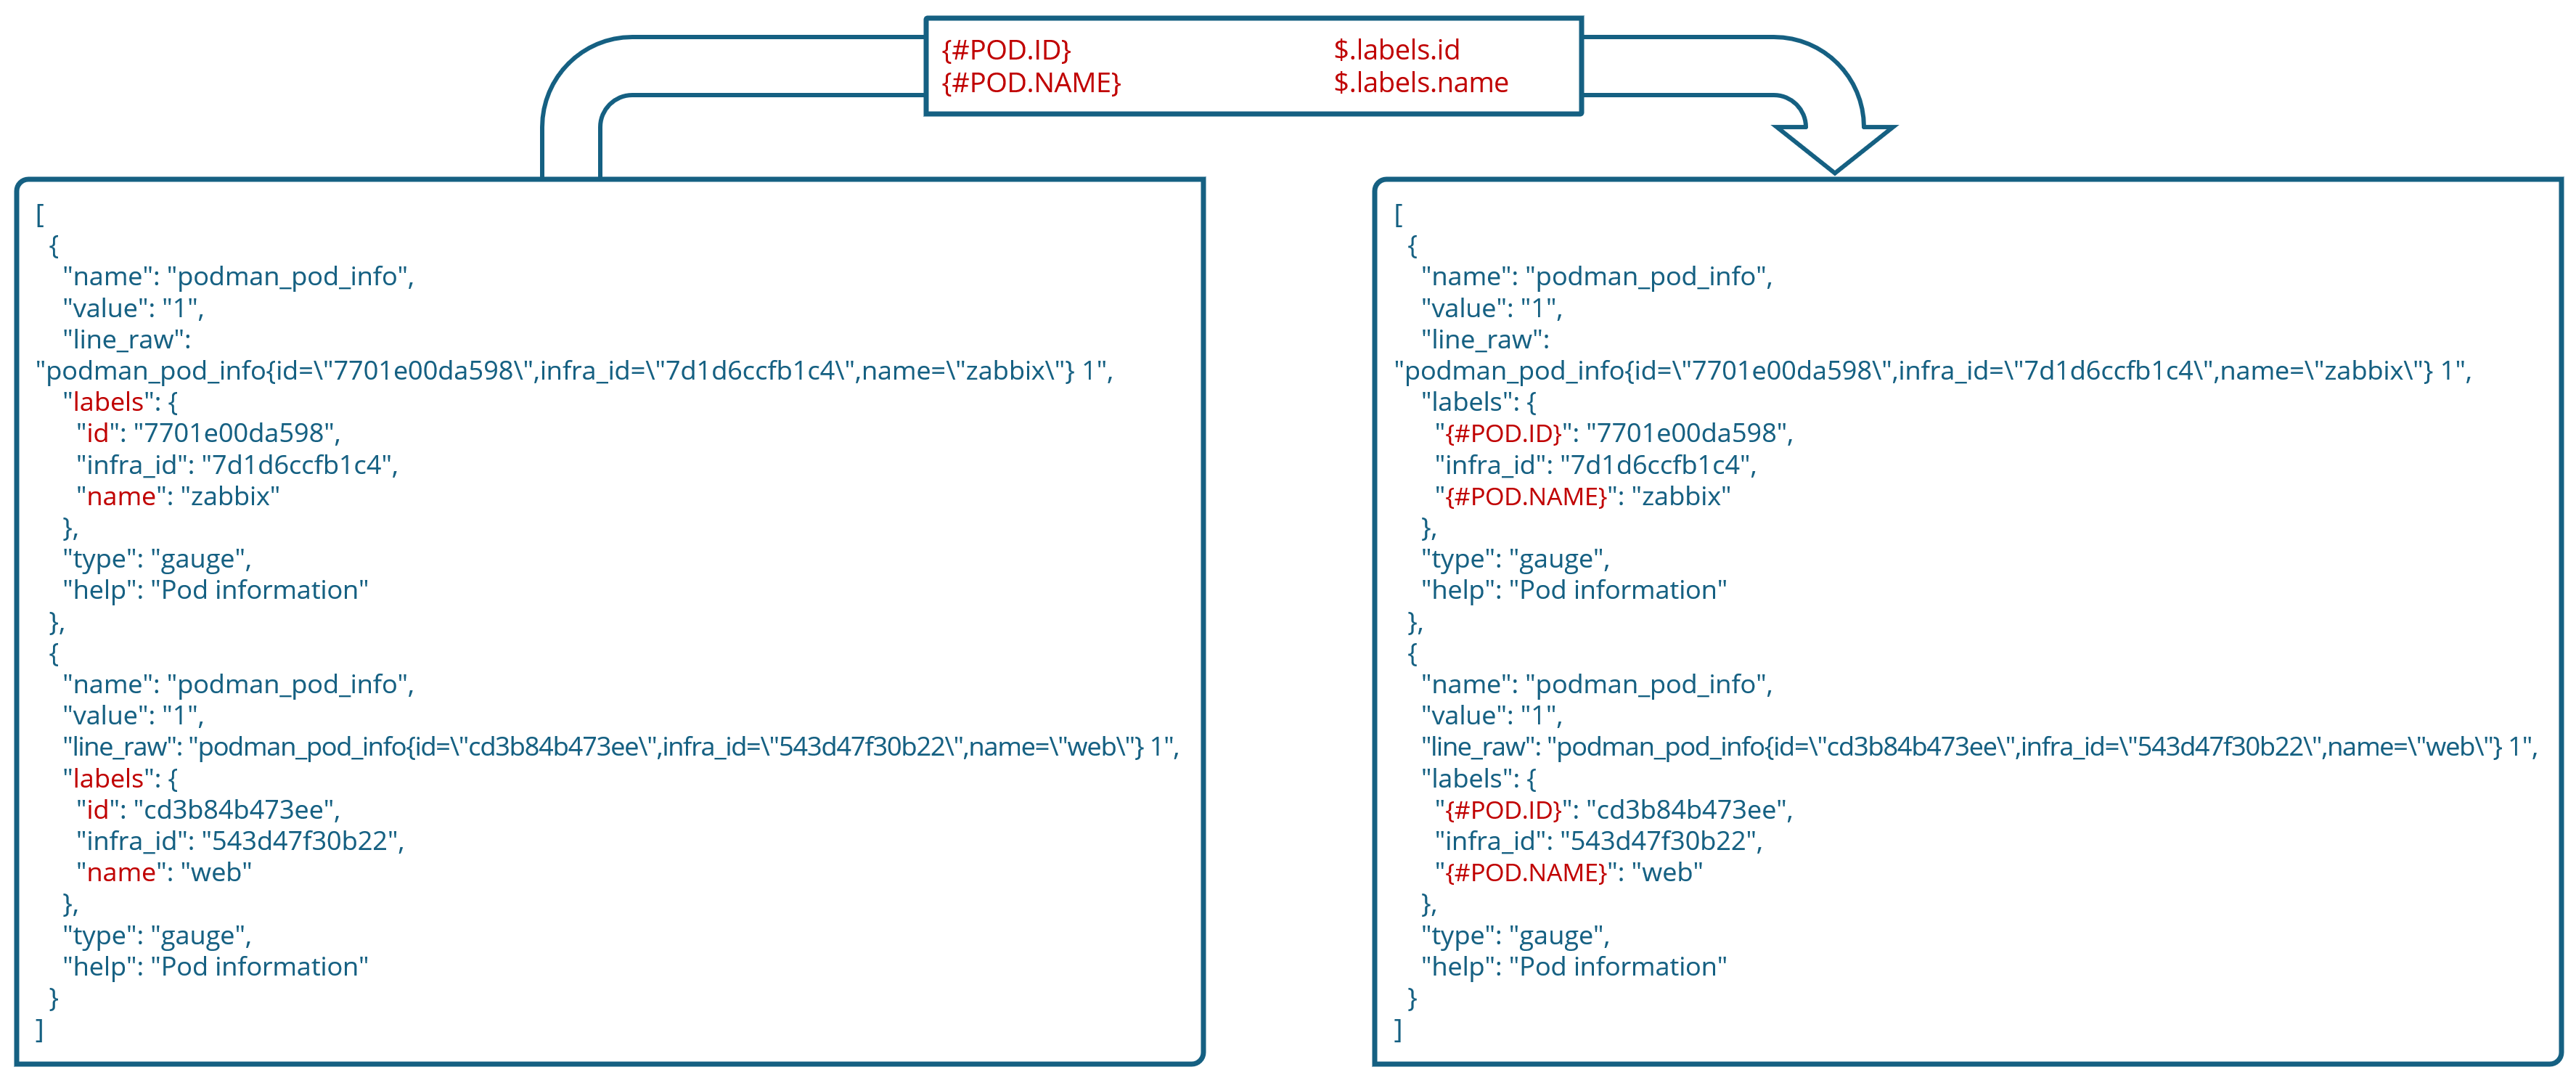
  ▪ {#CONTAINER.ID}        $.labels.id
  ▪ {#CONTAINER.NAME}      $.labels.name
Fig 1. Discovery rule: Container discovery
Fig 2. Discovery rule: Container discovery preprocessing tab
Fig 3. Discovery rule: Container discovery LLD macros tab

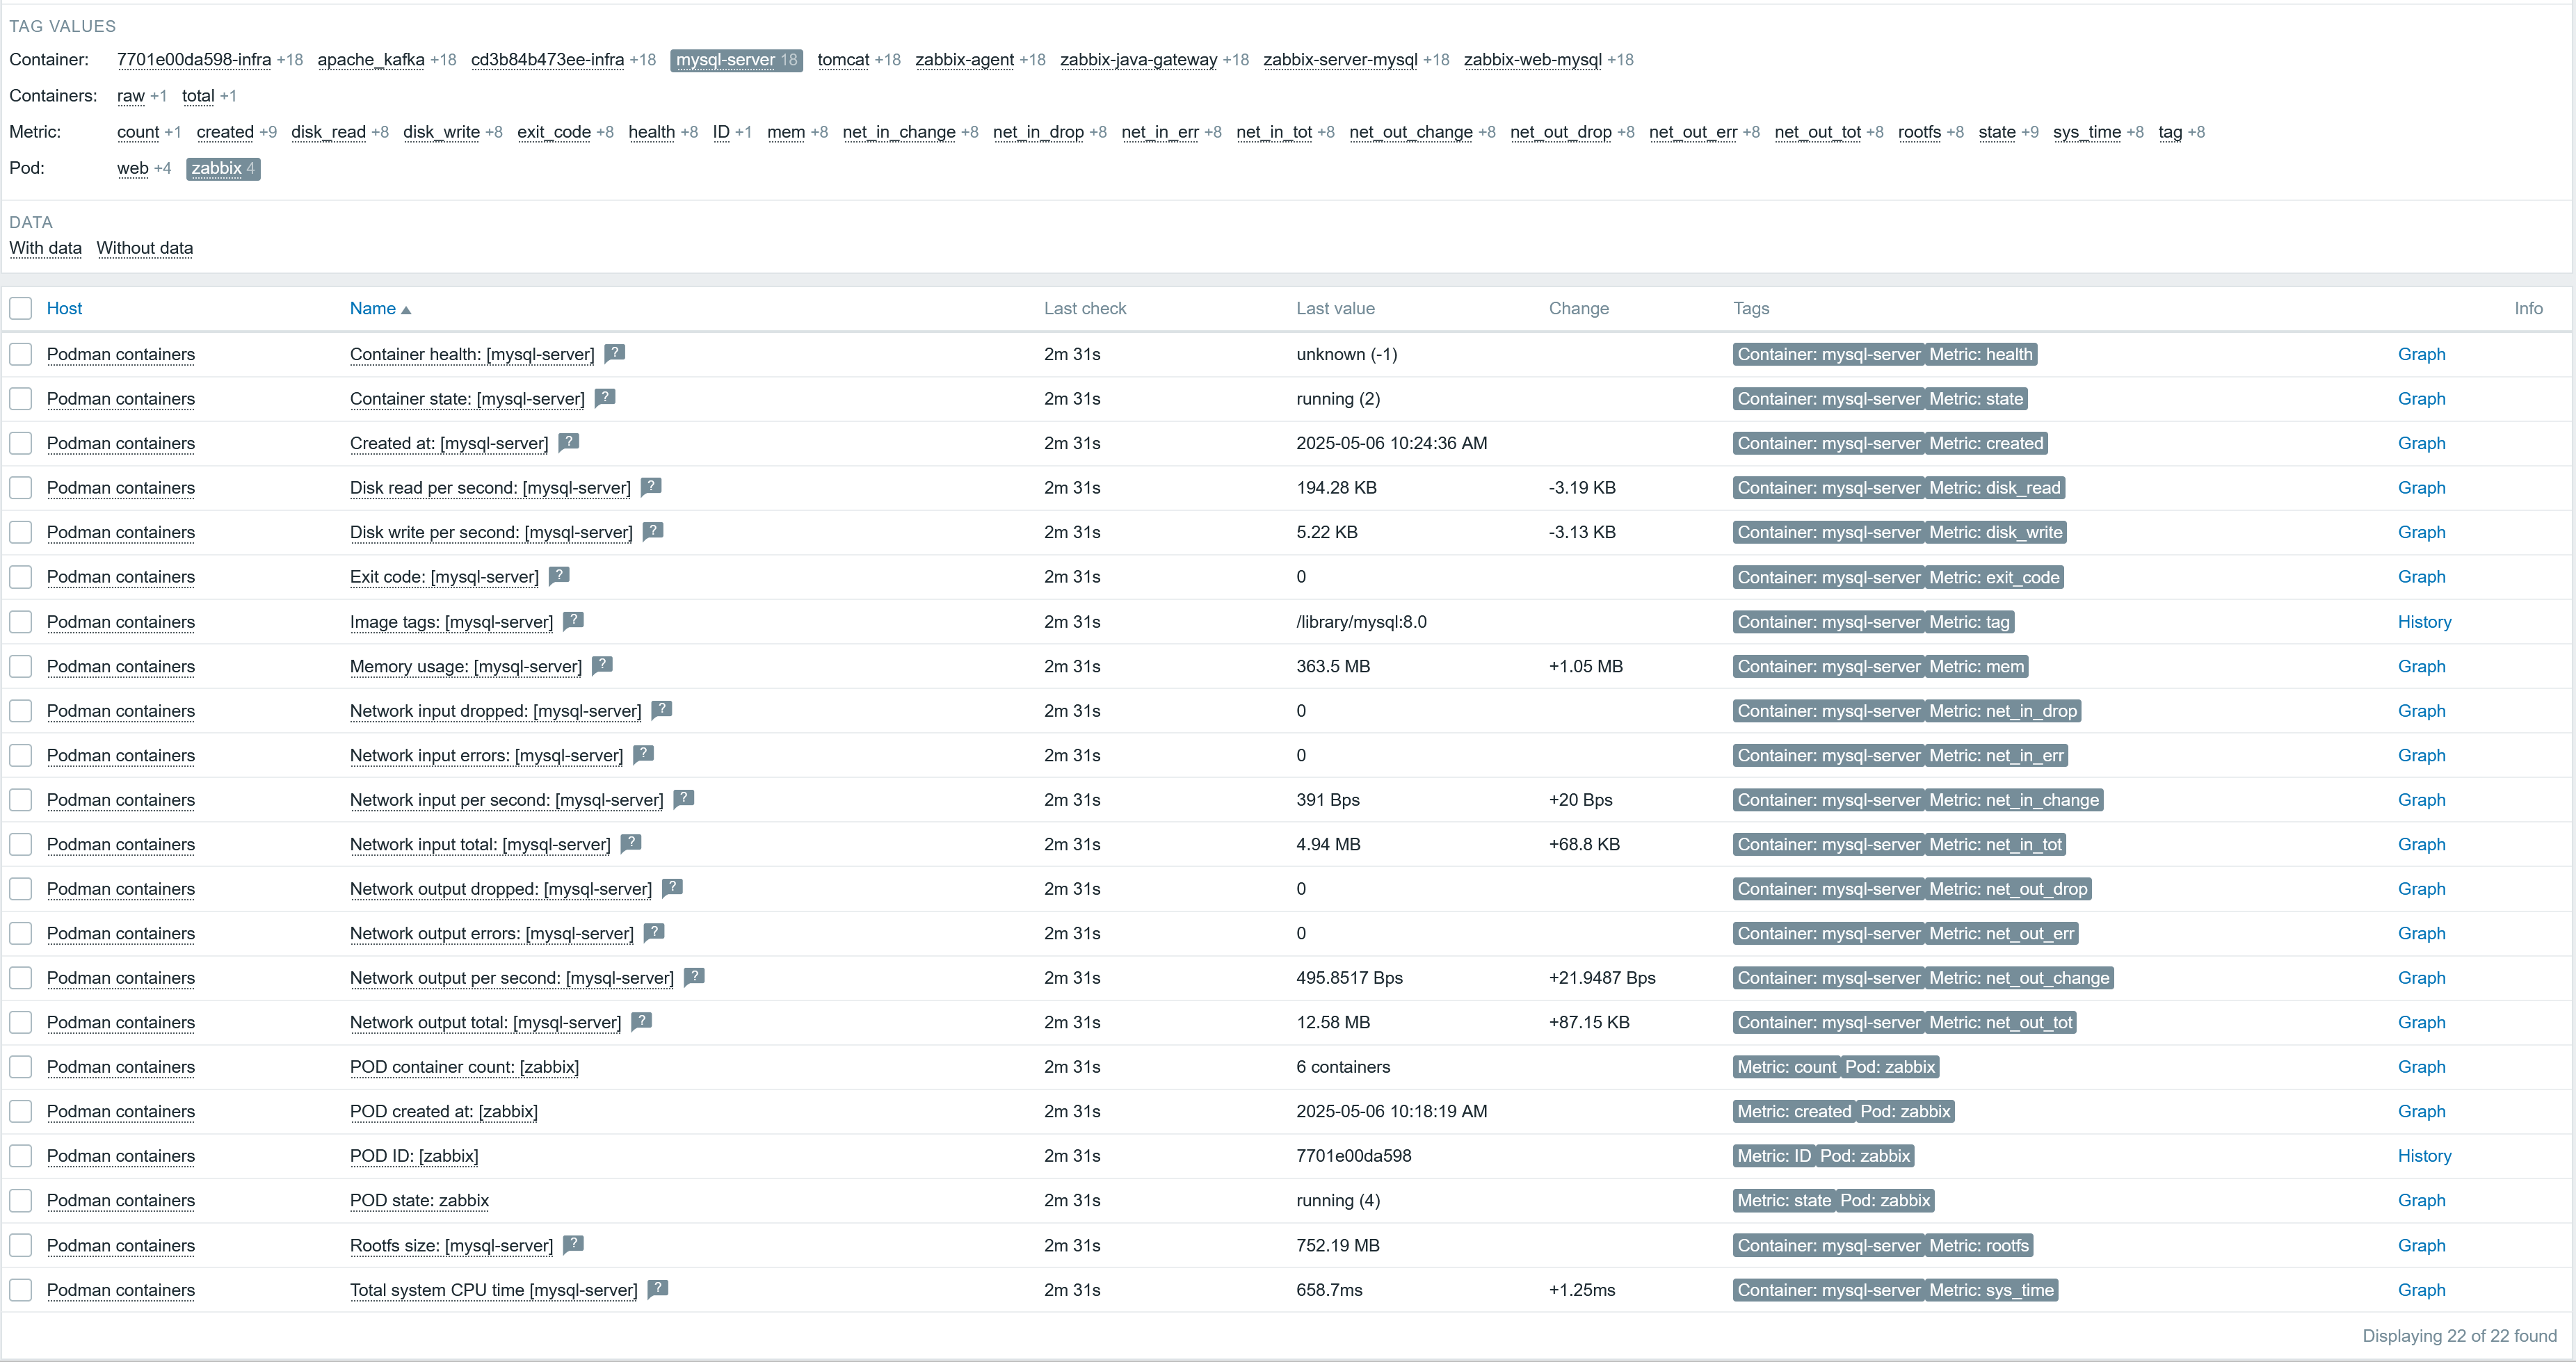
Next, different dependent item prototypes are created in this container discovery rule. As the Prometheus Podman exporter provides a lot of different metrics about the containers, I will create multiple such items: state, health, creation date, input/output network traffic information, and so on. So, check out what metrics can be acquired and use what is relevant for you.

You can also add a description of each item prototype. I am interested only in metrics with the discovered container ID macros, and I am not interested in what values are for the other fields, such as pod_id, pod_name, so I use ~”.*”, which matches any value. I will show the item prototype configuration screenshots of one of the item prototypes.

These item prototypes are similar to each other, with some minor differences, such as Prometheus patterns, or in some cases, with a different master item (item prototype as master item).

Fig 4. Discovery rule preprocessing step: Prometheus to JSON with pattern podman_container_info
Fig 5. Discovery rule LLD macros: assigning relevant JSONPATH to LLD macros

Creating a template discovery rule: Item prototypes

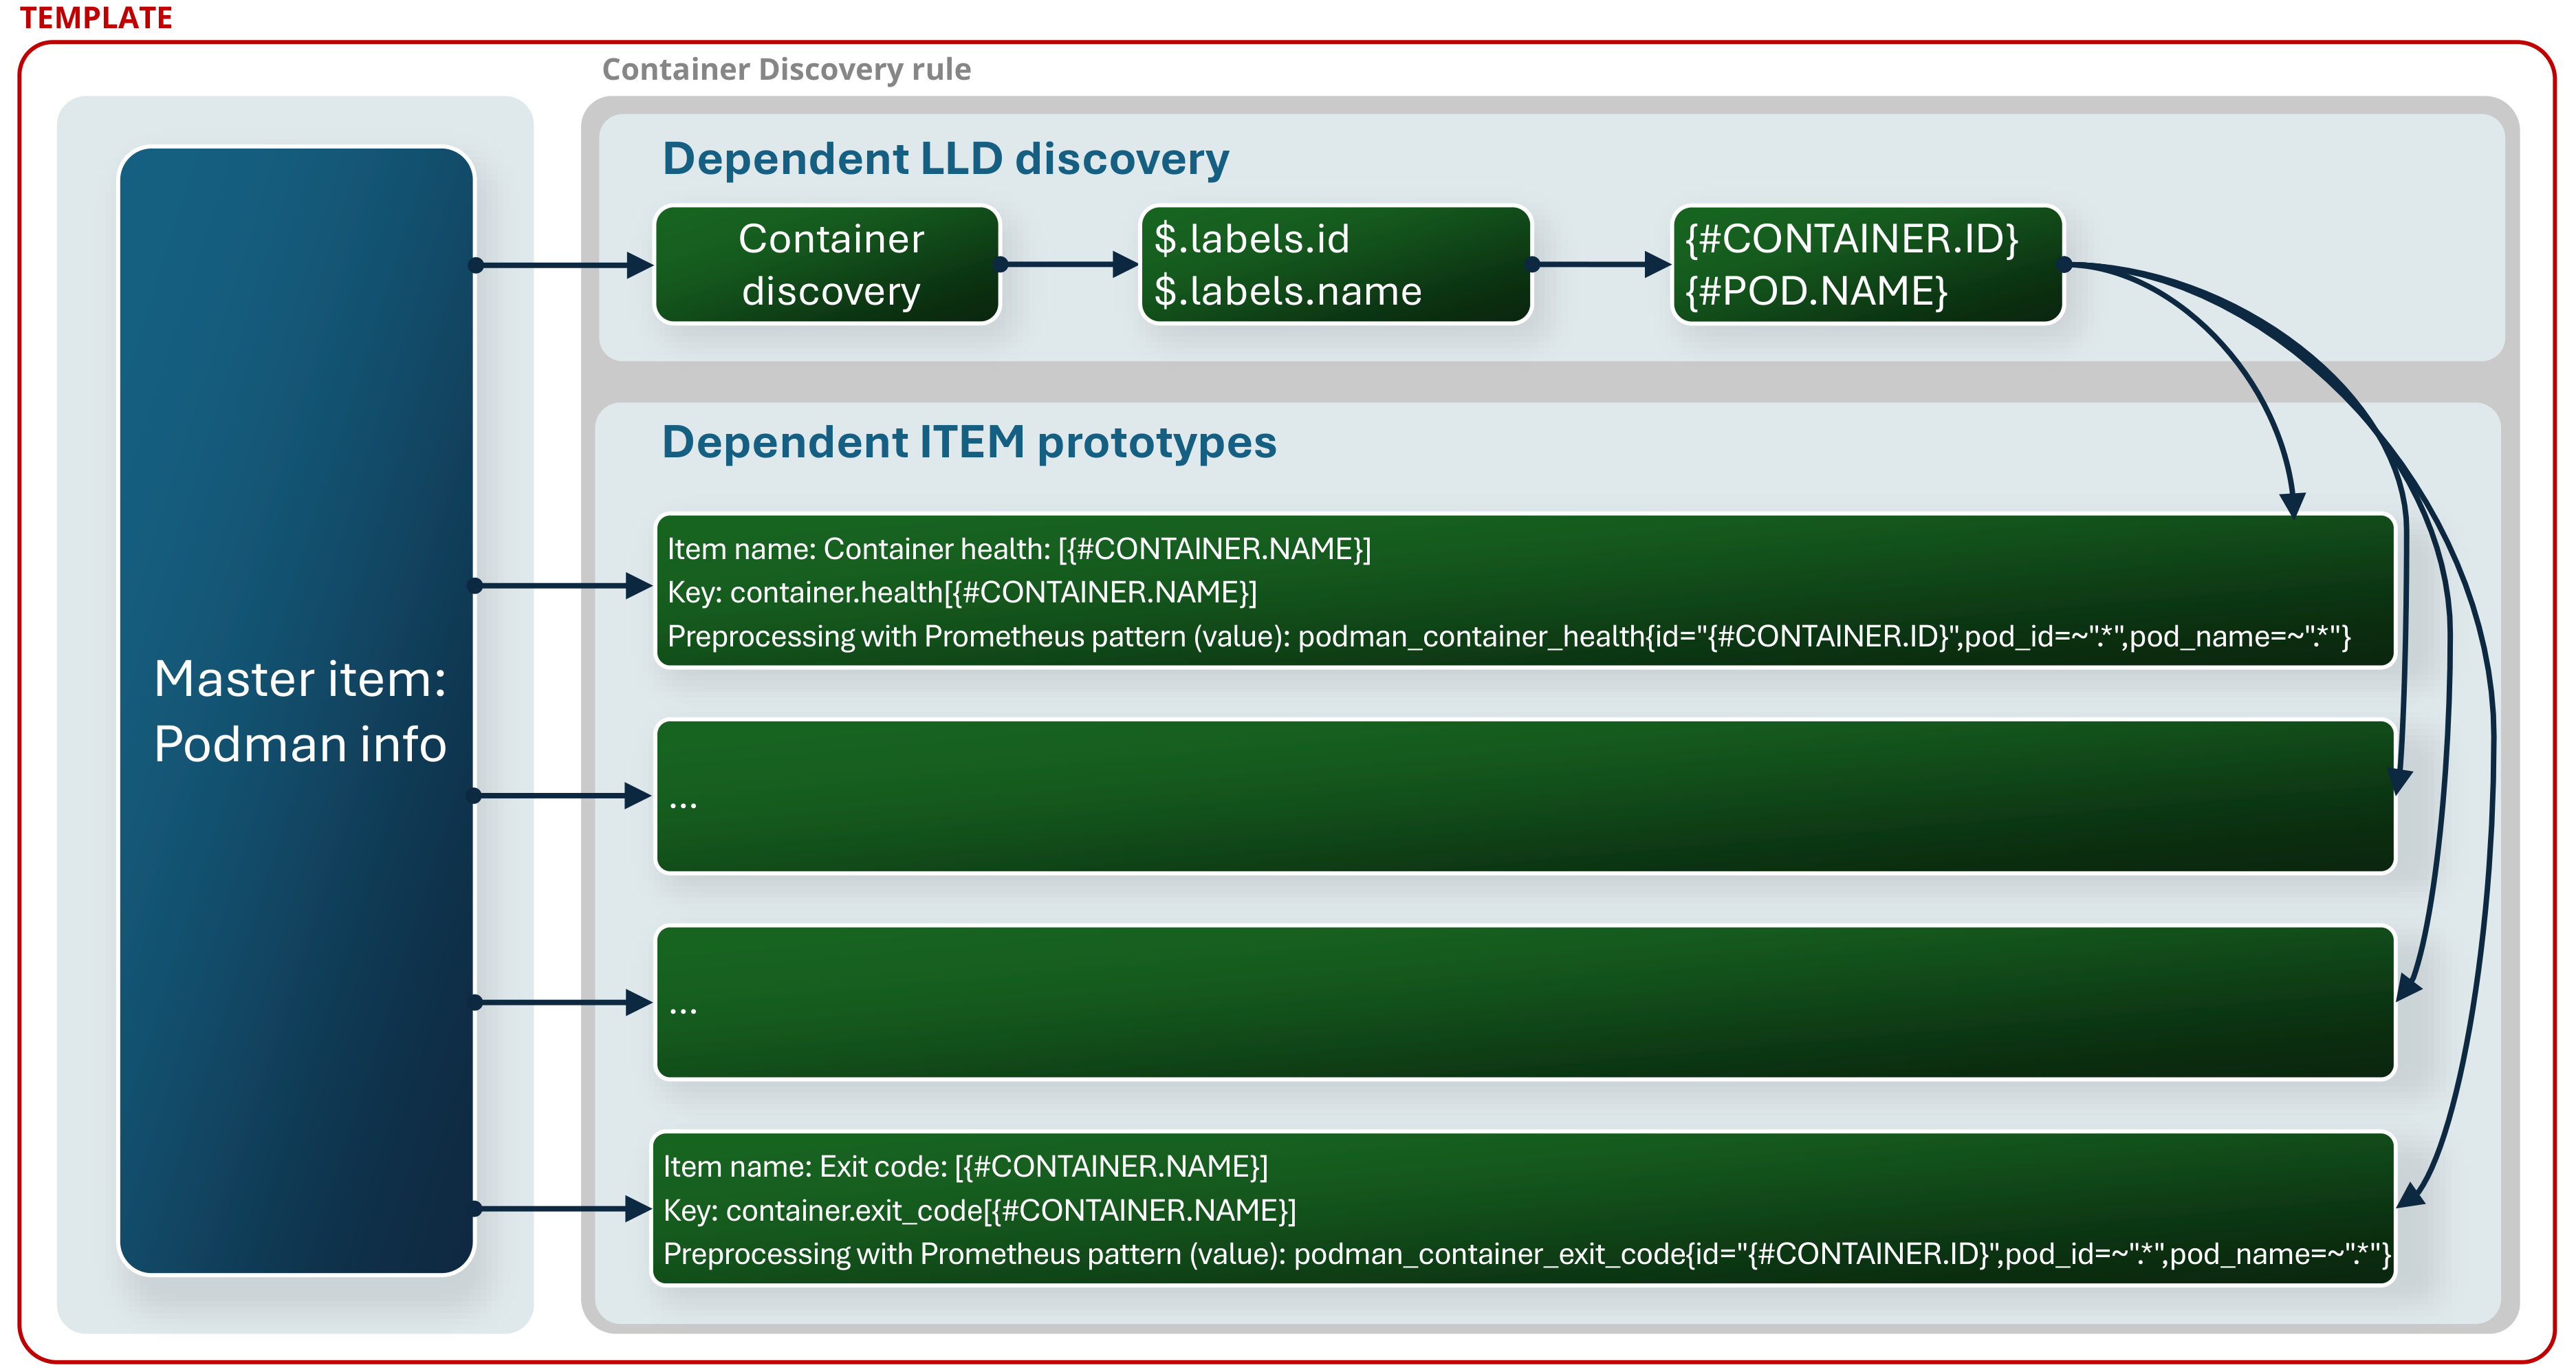
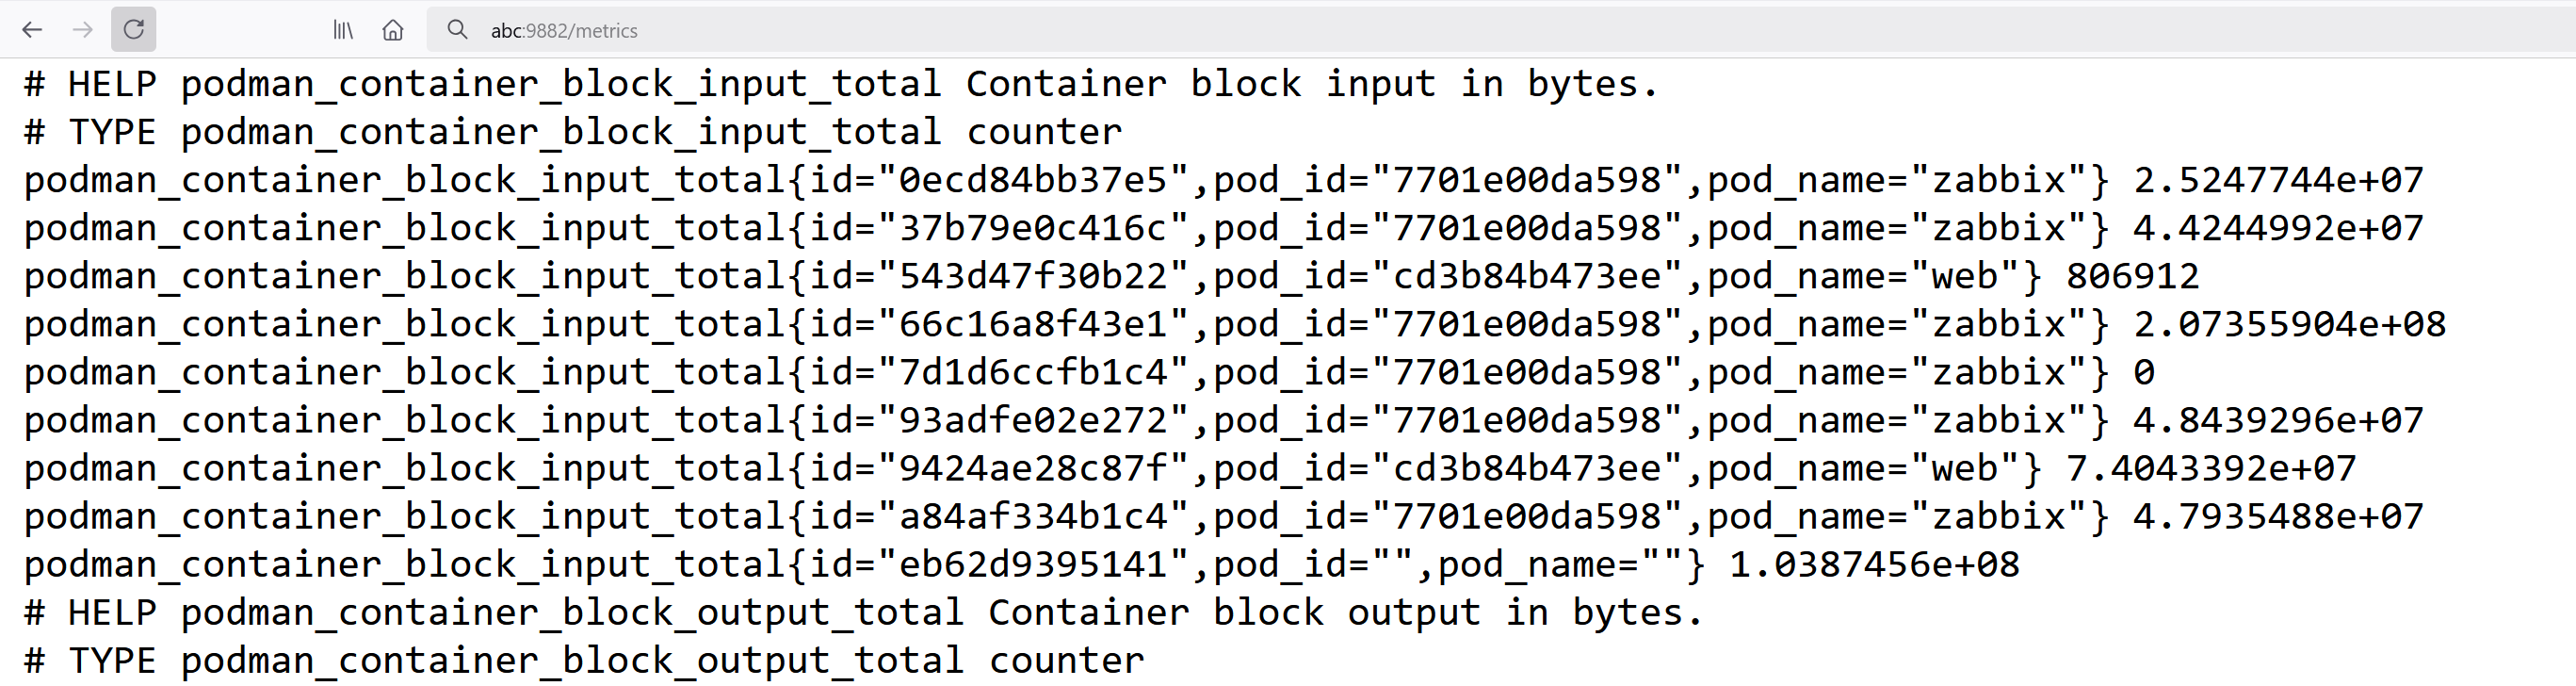
After the containers have been discovered, we have to create item prototypes. These prototypes will also be dependent item prototypes and will use the same item as the discovery rule: Podman info. Prometheus Podman exported returns a lot more metrics for the containers than it did for the pods.

You can get container metrics such as container health, state, creation date, disk read/write, memory usage, network usage, and more. In this blog post, I have added most of them, so check what metrics are relevant to your monitoring needs and start monitoring.

Fig 6. Low-level discovery rule and item prototypes based on the same item.

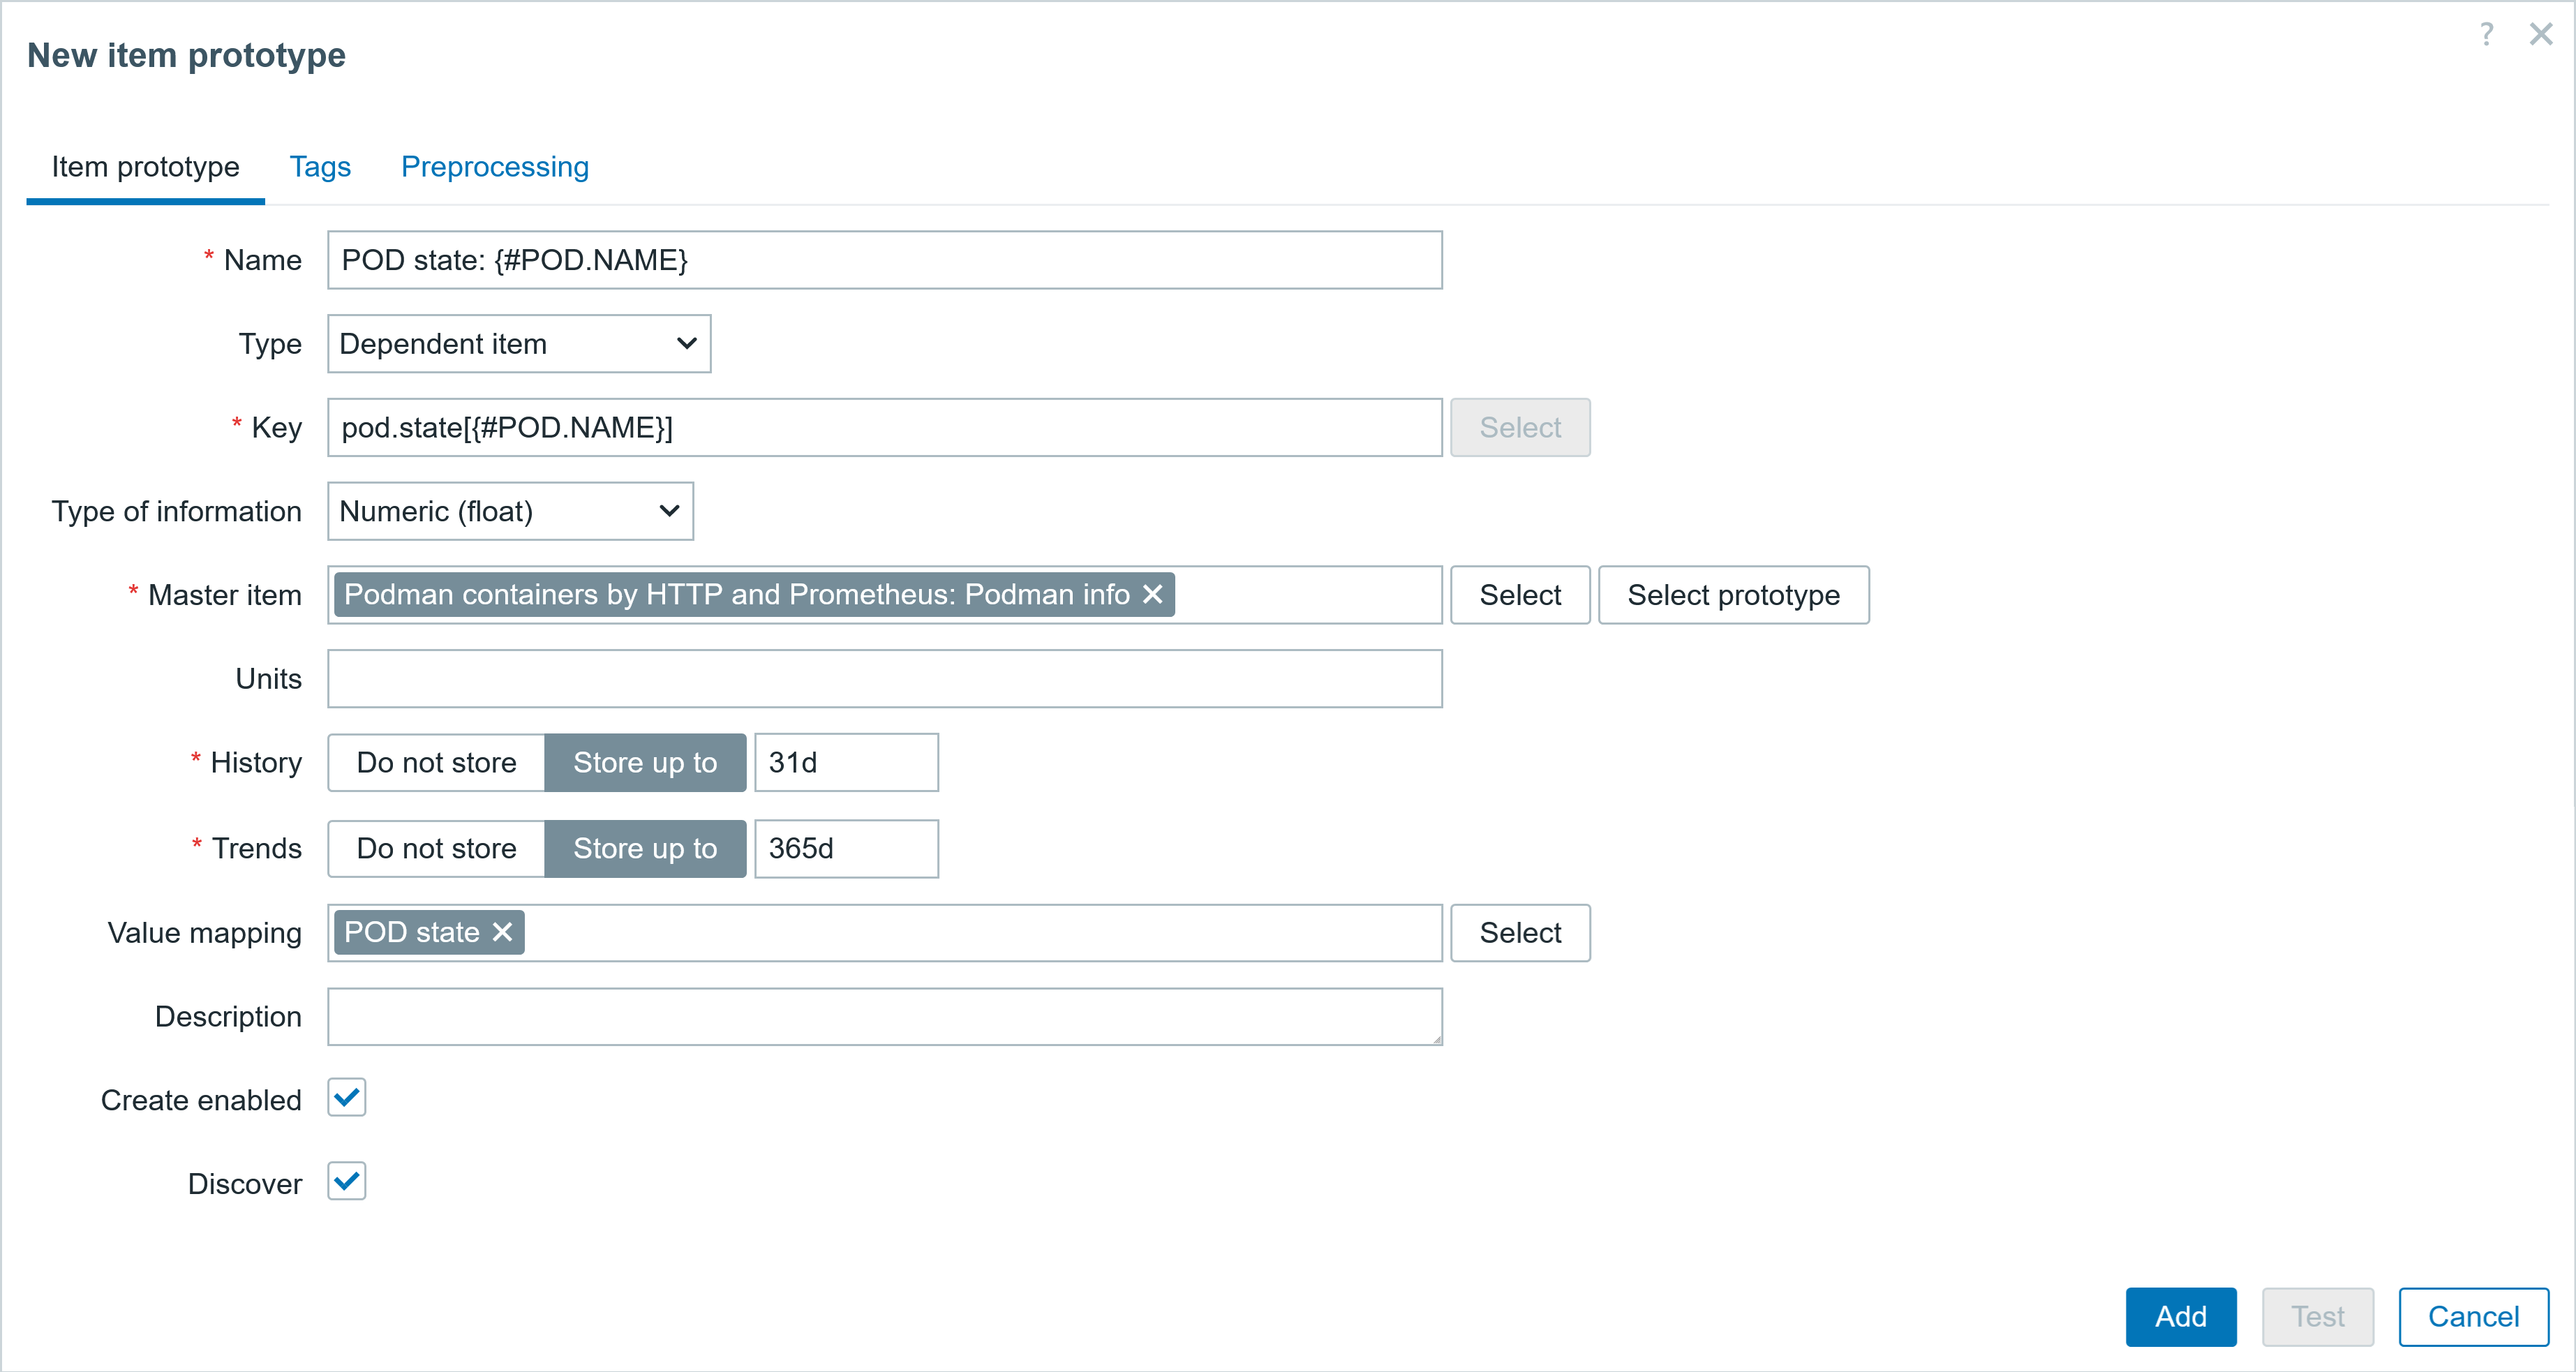
The screenshots of the item prototype is shown below.

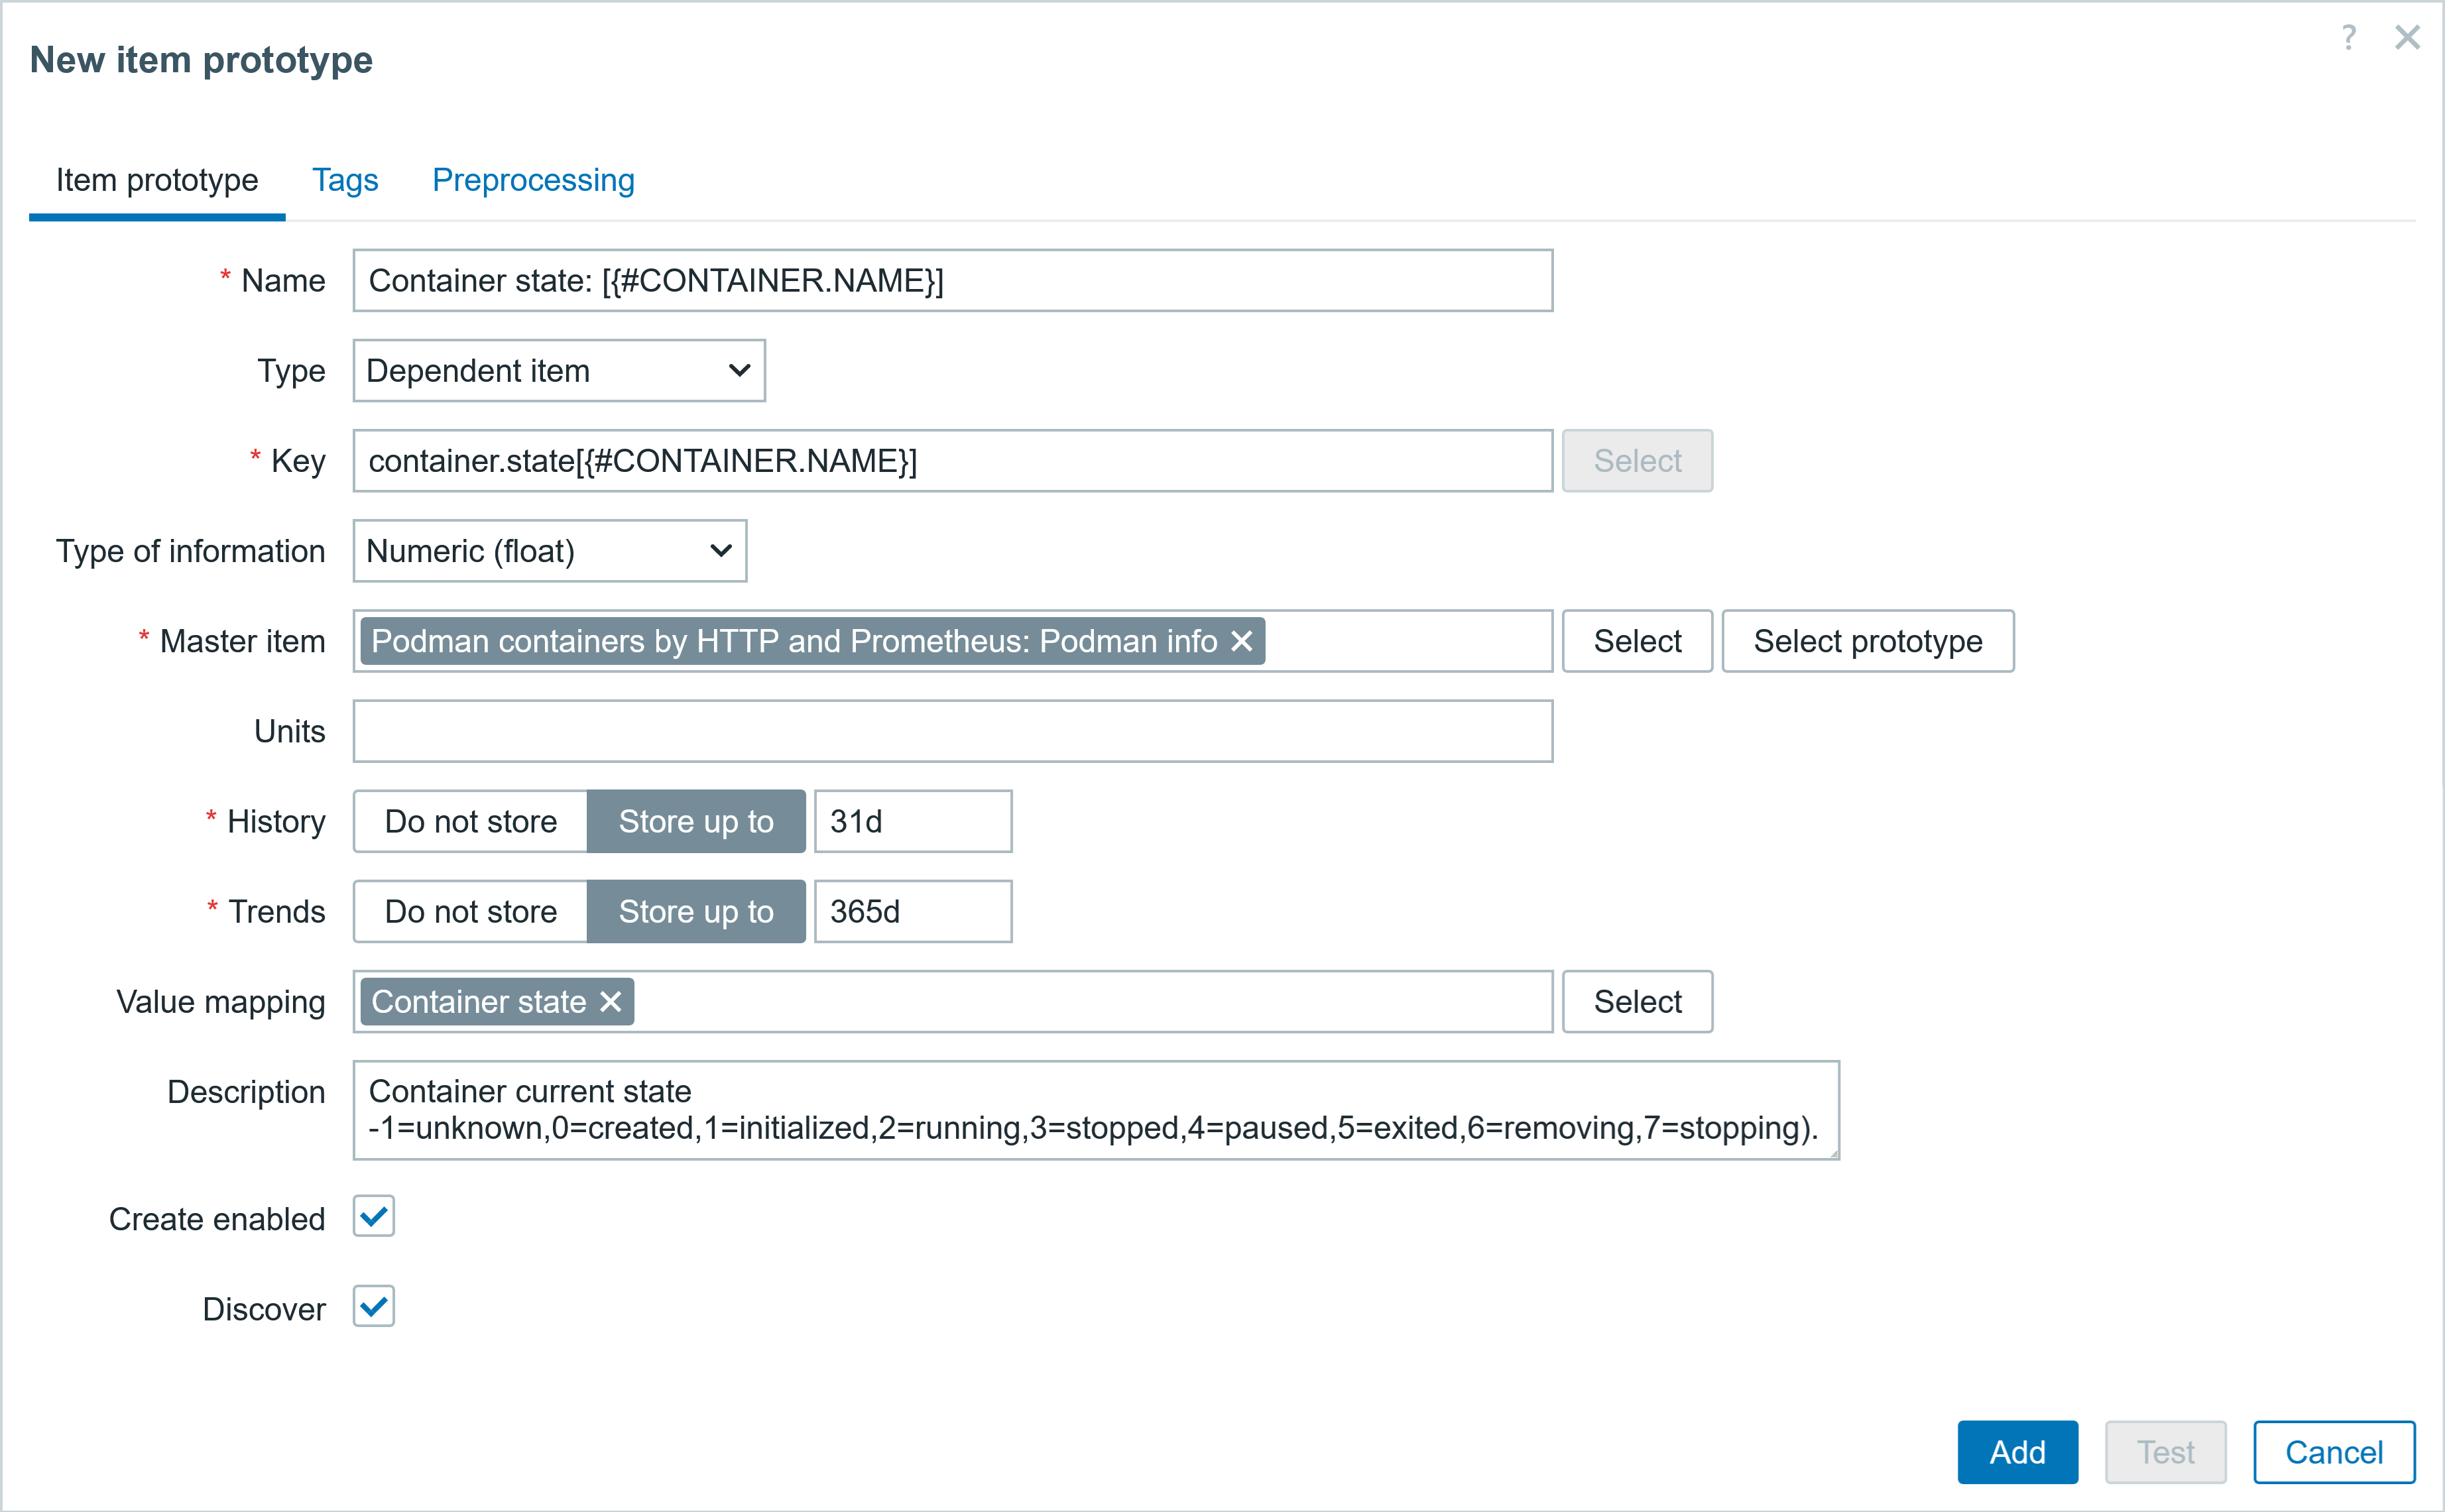
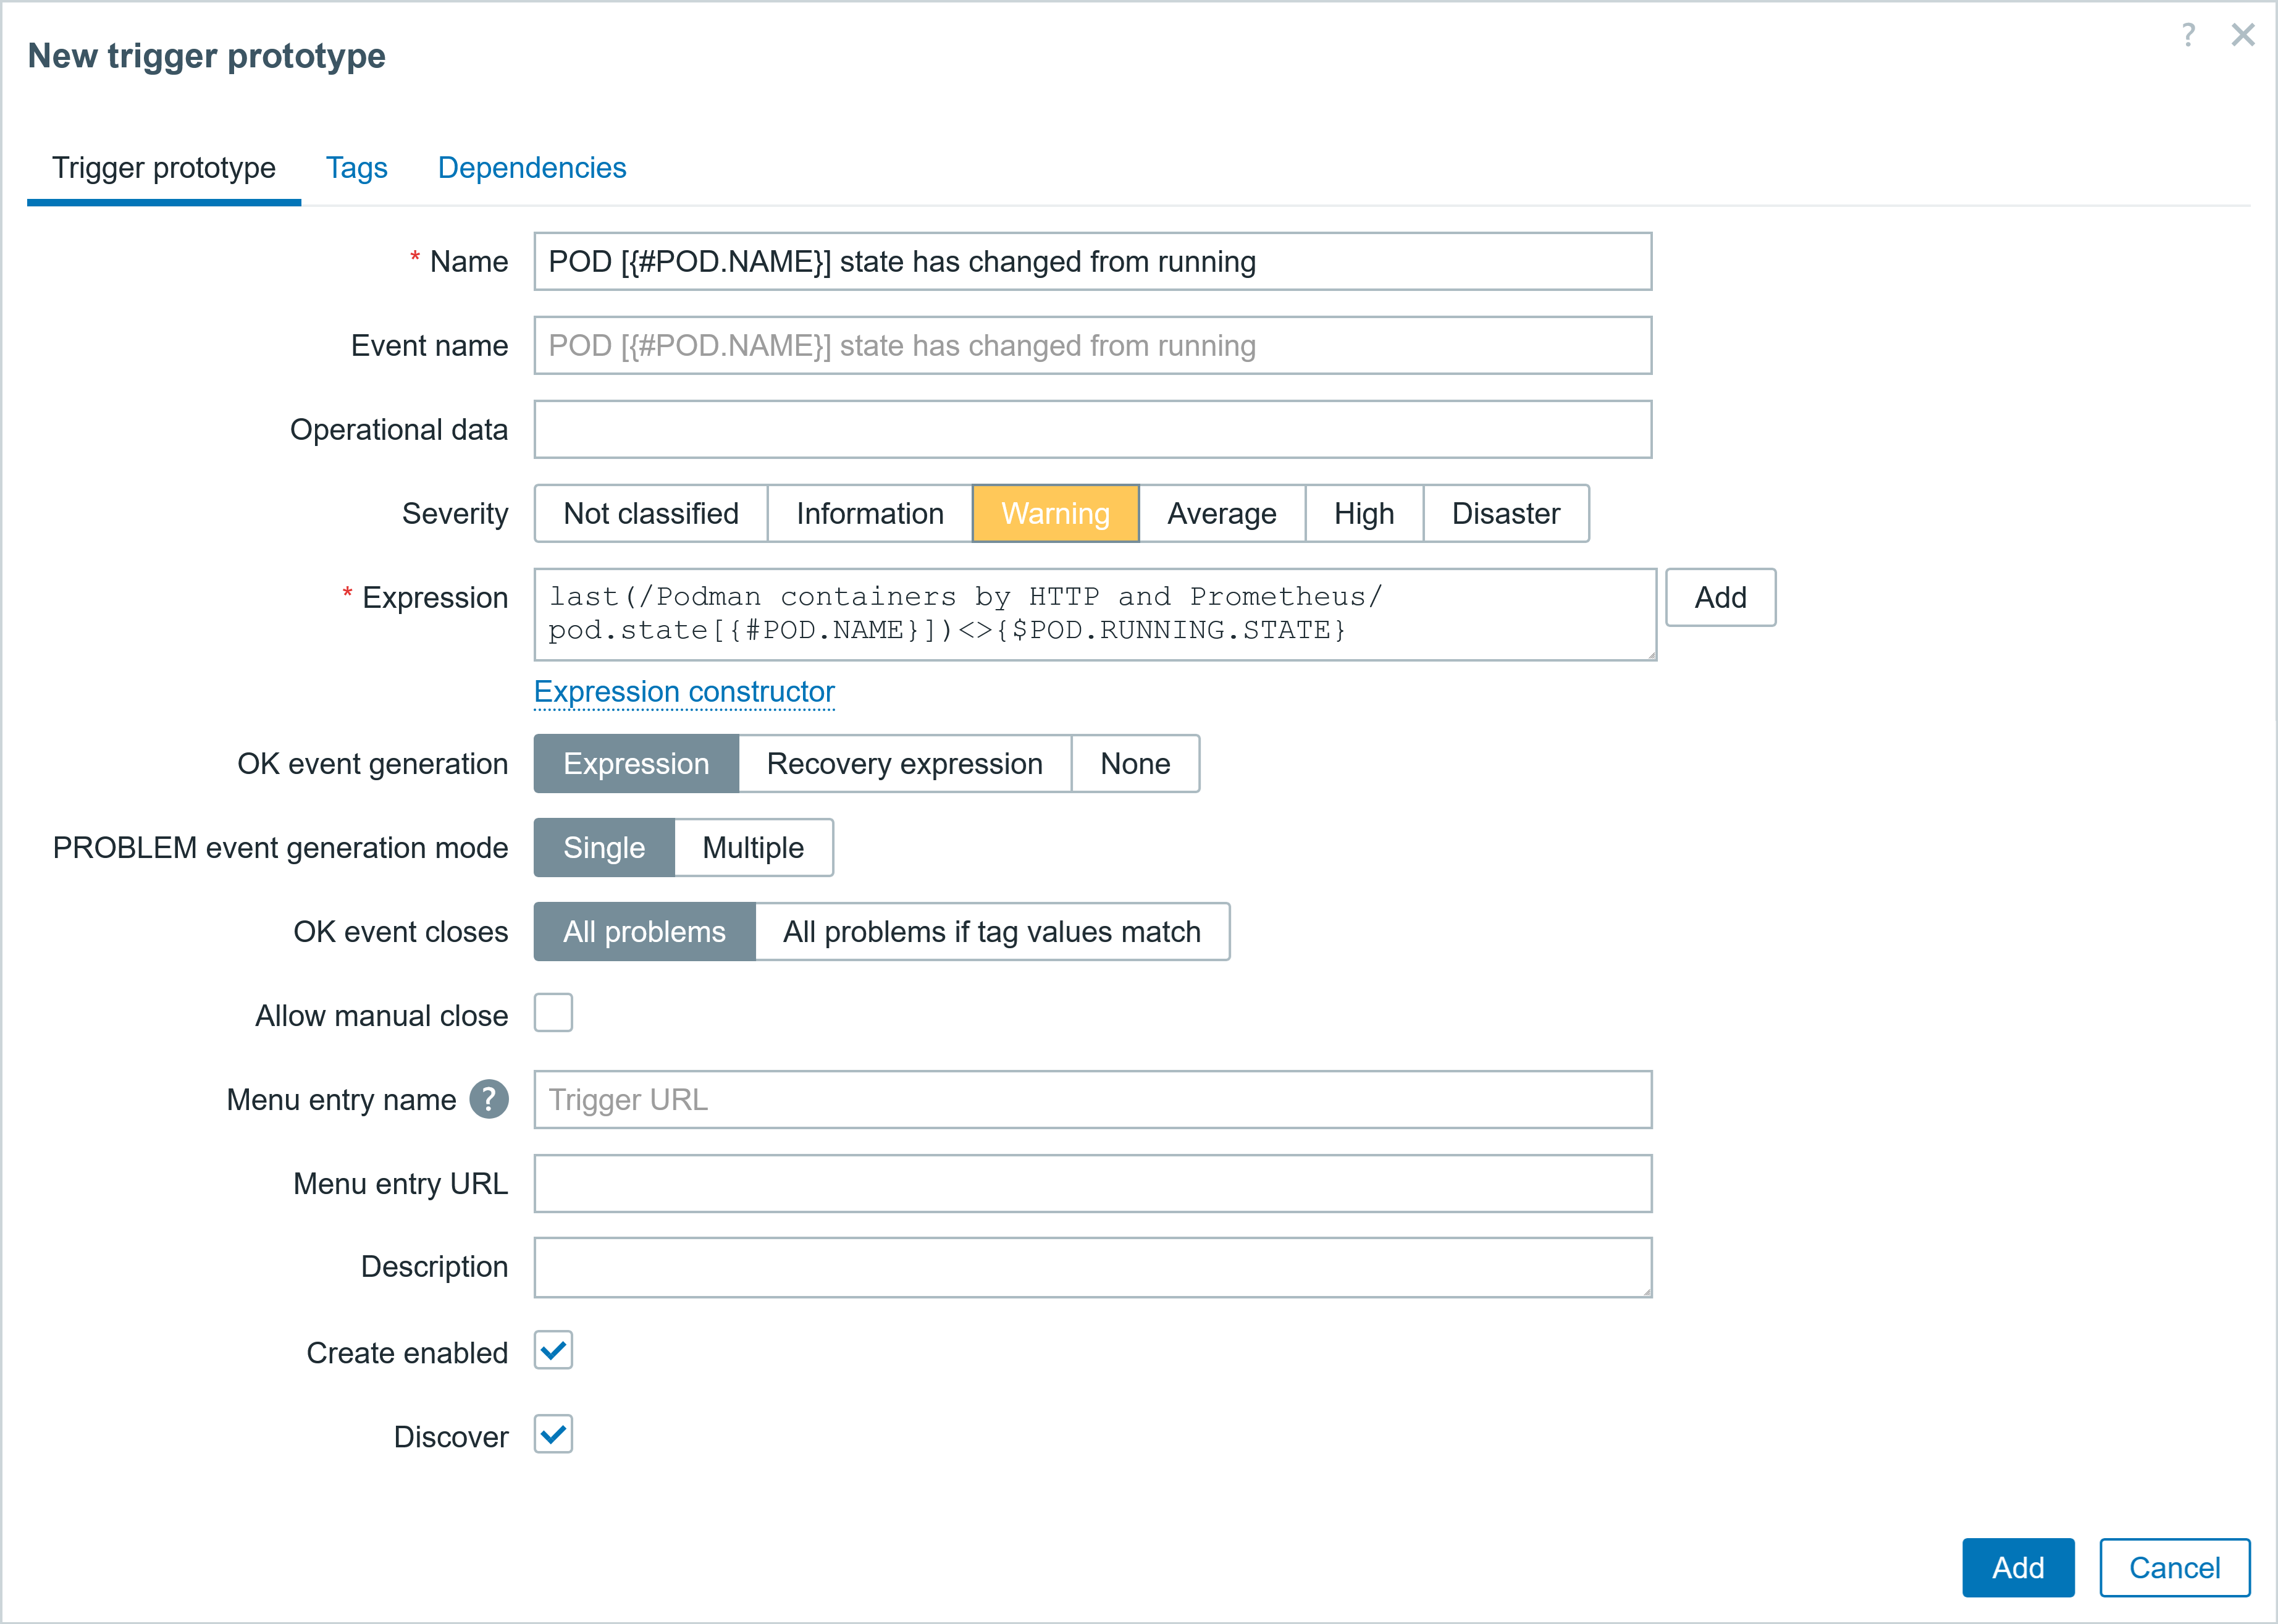
Fig 7. Container state item prototype tab
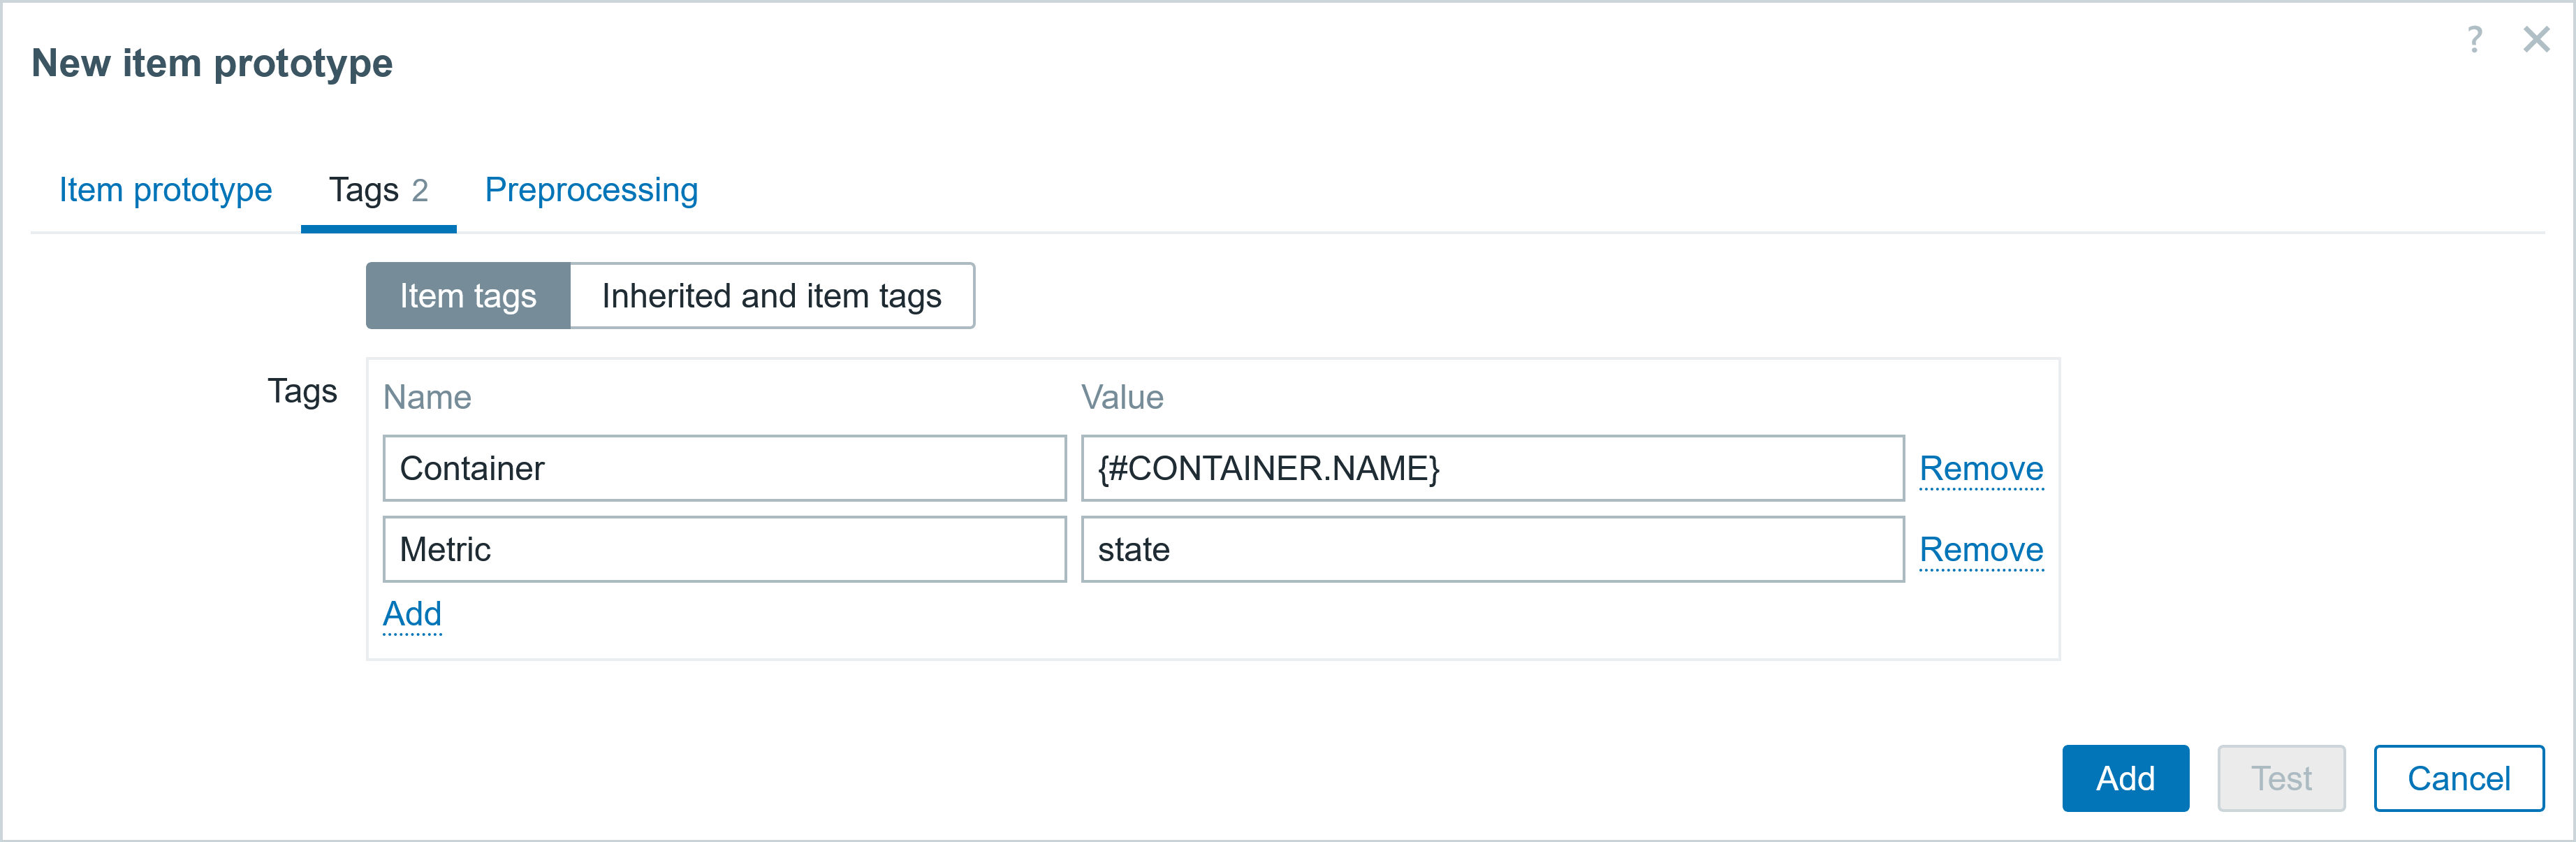
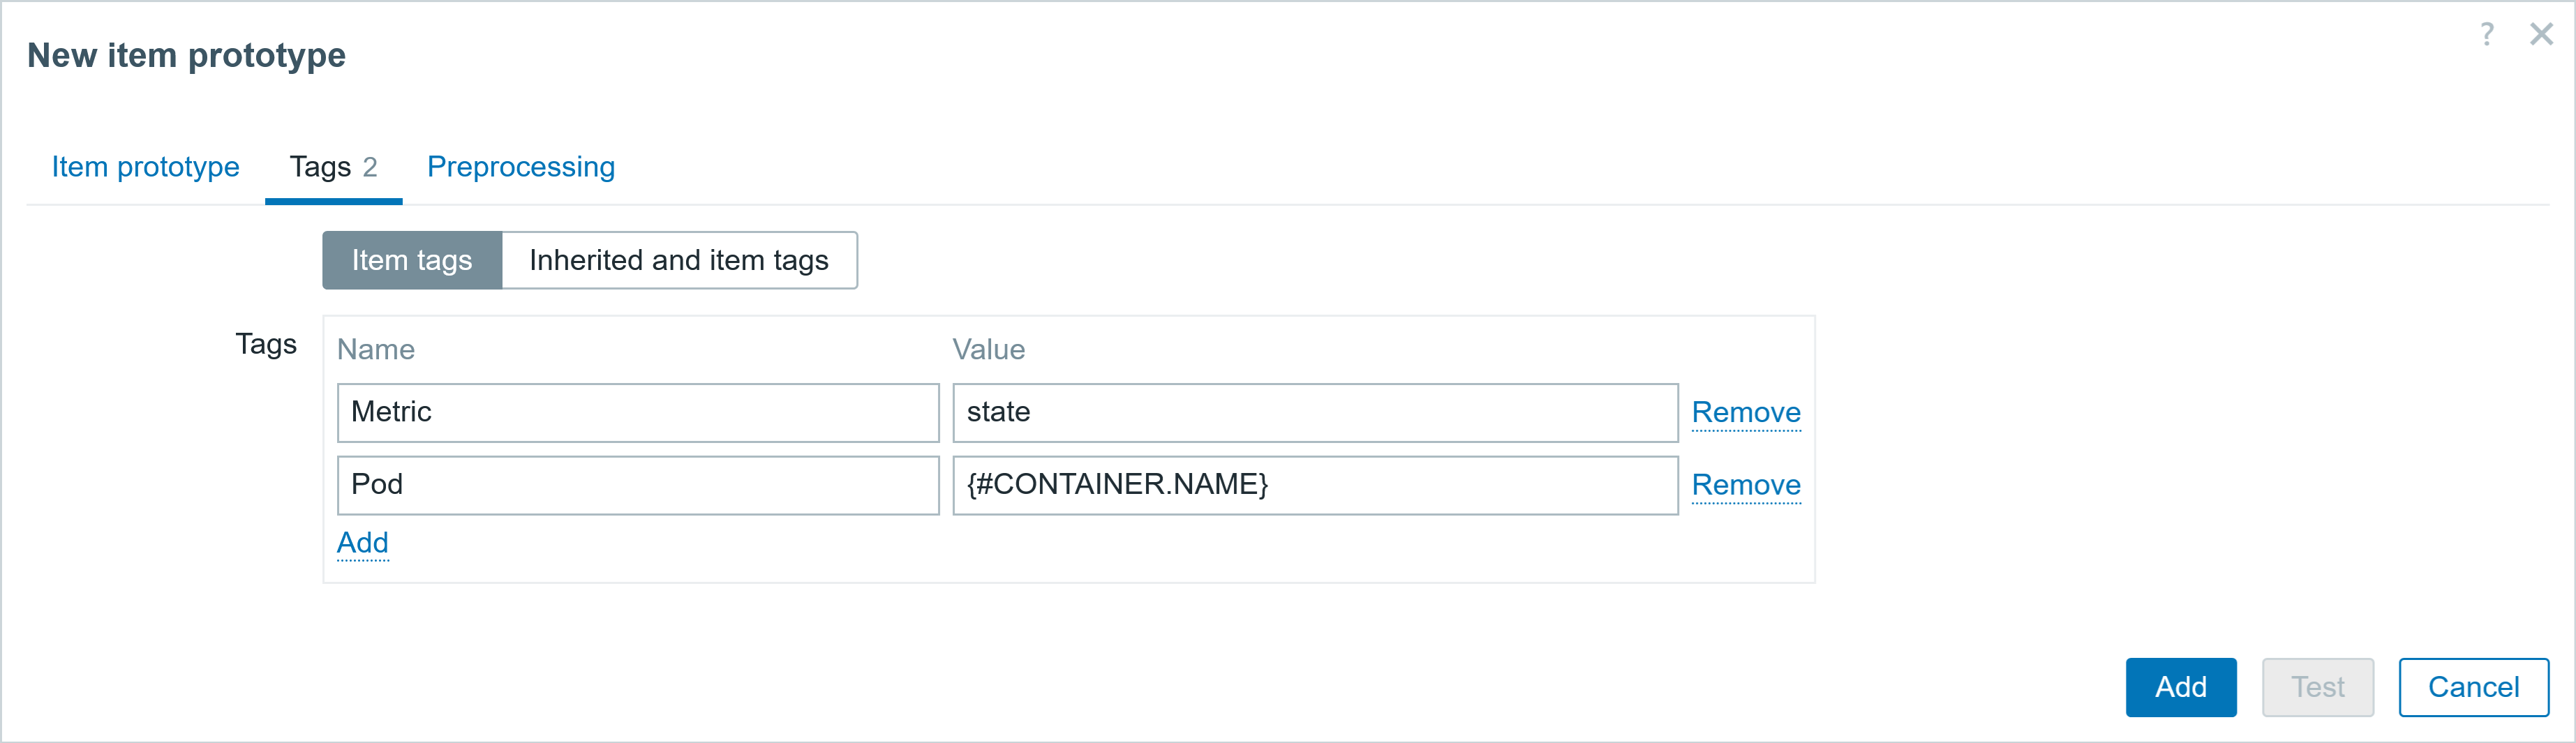
Fig 8. Container state item prototype tag tab
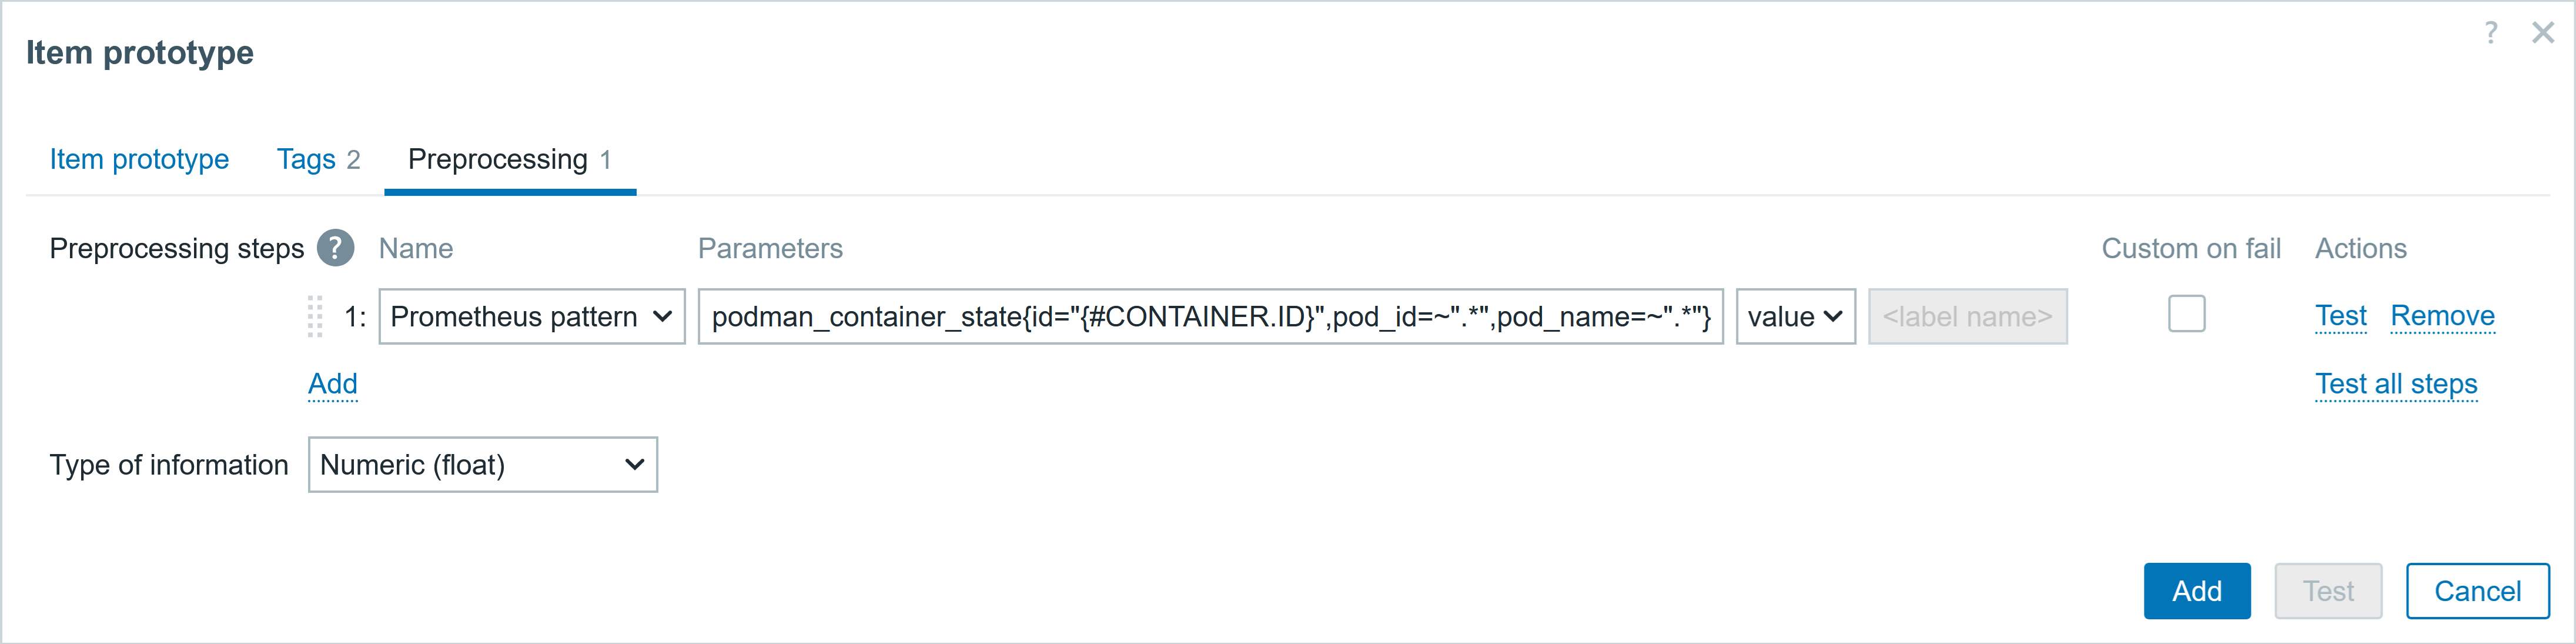
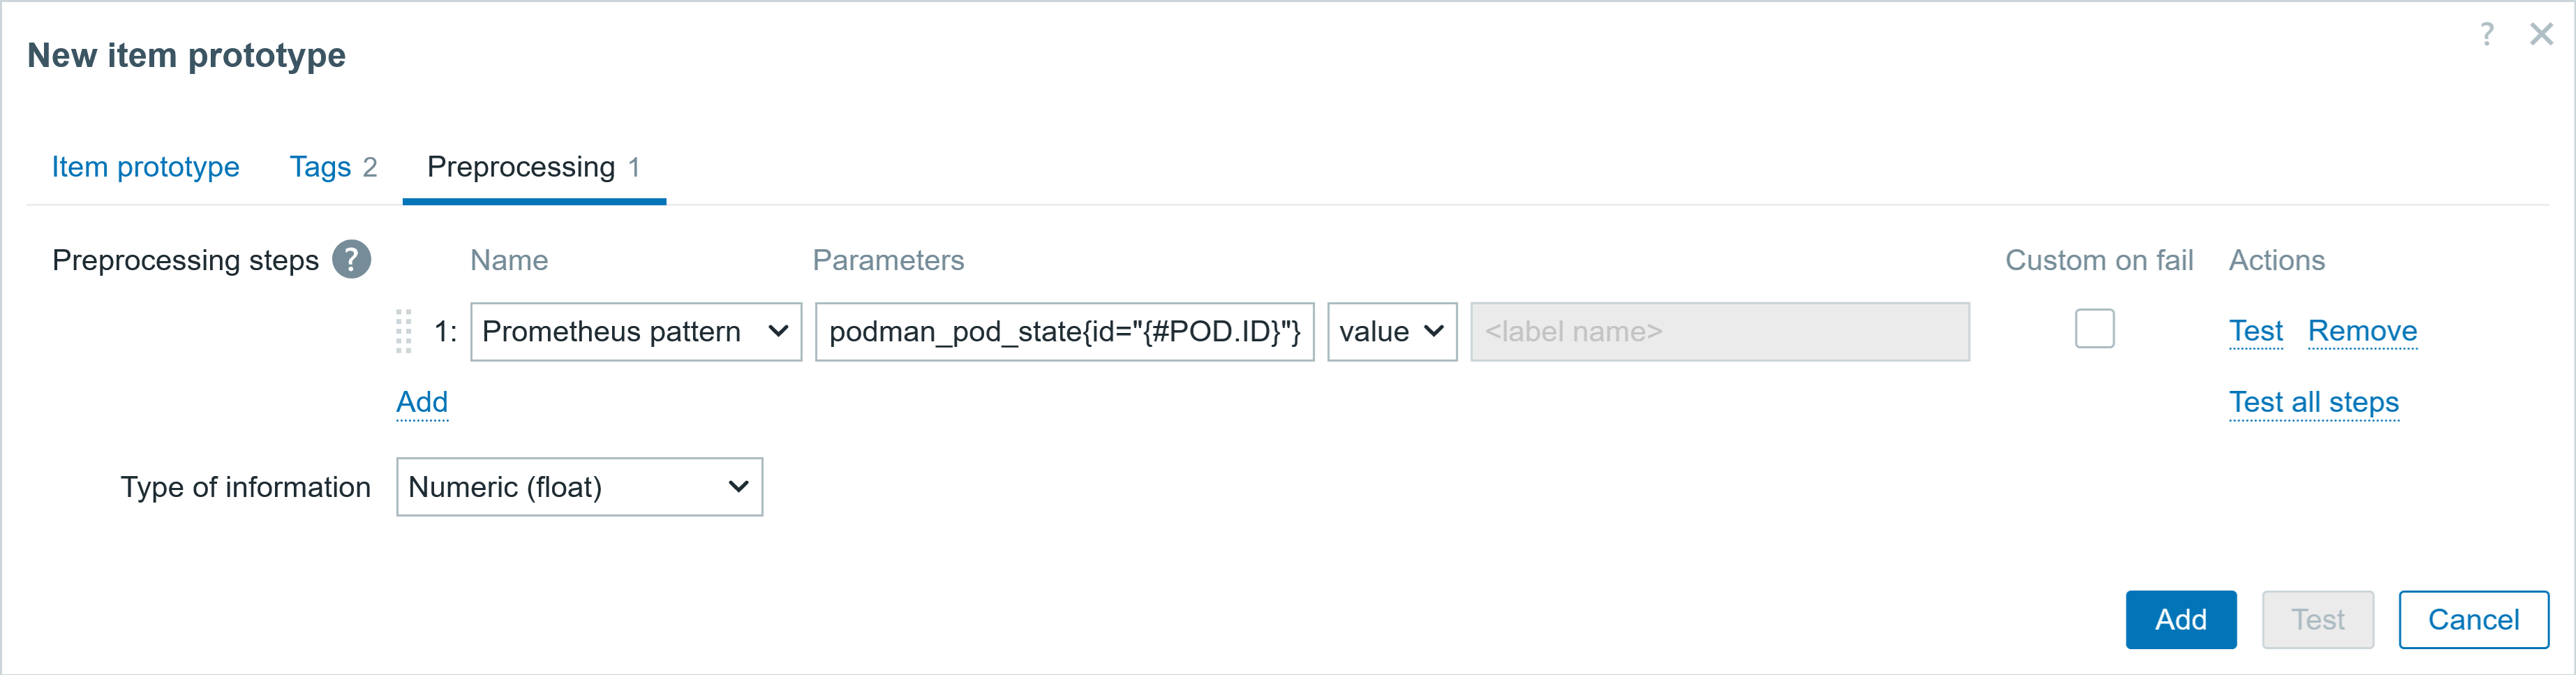
Fig 9. Container state item prototype preprocessing tab

Remember, you can also test these item prototypes in the preprocessing step – just copy the Prometheus exporter data and set the relevant macro to value you want to check.

The configuration parameters of the item prototypes are shown below. There are a lot of metrics you can monitor, but remember to monitor what is relevant and necessary for you.

Template: Podman containers by HTTP and Prometheus; Discovery rule: Container discovery

● Item prototype #1
  ▪ Name: 		Container health: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.health[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 
♦ Tags (name:value) 	
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:health		
♯ Preprocessing
  ▪ Prometheus pattern 	podman_container_health{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #2
  ▪ Name: 		Container state: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.state[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		
♦ Tags (name:value)  			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:state		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_state{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #3
  ▪ Name: 		Created at: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.created[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		unixtime
♦ Tags (name:value) 		
  ▪ Container:{#CONTAINER.NAME}	
  ▪Metric:created		
♯ Preprocessing
  ▪ Prometheus pattern 	podman_container_created_seconds{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #4
  ▪ Name: 		Disk read per second: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.disk.read[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags (name:value) 	
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:disk_read		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_block_output_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value
  ▪ Change per second

● Item prototype #5
  ▪ Name: 		Disk write per second: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.disk.write[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags (name:value) 	
  ▪ Container:{#CONTAINER.NAME}	 
  ▪ Metric:disk_write		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_block_input_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value
  ▪ Change per second

● Item prototype #6
  ▪ Name: 		Exit code: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.exit_code[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
    ▪ Master item	Podman containers by HTTP and Prometheus: Podman info
▪ Units: 			
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:exit_code	
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_exit_code{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #7
  ▪ Name: 		Image tags: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.image.tags[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Character
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 			
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:tag
♯ Preprocessing
▪ Prometheus pattern podman_container_info{id="{#CONTAINER.ID}",image=~".*",name=~".*",pod_id=~".*",pod_name=~".*",ports=~".*"} label image
  ▪ Regular expression	\.*(\/.\w.*)	\1

● Item prototype #8
  ▪ Name: 		Memory usage: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.mem[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:mem		
♯ Preprocessing
  ▪ Prometheus pattern podman_container_mem_usage_bytes{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #9
  ▪ Name: 		Network input dropped: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.in.drop[{#CONTAINER.NAME}]
  ▪ Type of inf: Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		packets
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_in_drop		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_input_dropped_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #10
  ▪ Name: 		Network input errors: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.in.errors[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_in_err		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_input_errors_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #11
  ▪ Name: 		Network input total: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.in.total[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_in_tot
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_input_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #12
  ▪ Name: 		Network input per second: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.in.change[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		prototype - Network input total: [{#CONTAINER.NAME}] 
  ▪ Units: 		Bps
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_in_change
♯ Preprocessing
  ▪ Change per second

● Item prototype #13
  ▪ Name: 		Network output dropped: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.out.drop[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_out_drop	
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_output_dropped_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #14
  ▪ Name: 		Network output errors: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.out.errors[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_out_err	
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_output_errors_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #15
  ▪ Name: 		Network output total: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.out.total[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_out_tot	
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_output_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #16
  ▪ Name: 		Network output per second: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.out.change[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		prototype - Network output total: [{#CONTAINER.NAME}]
  ▪ Units: 		Bps
♦ Tags 			 
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_out_change
♯ Preprocessing
  ▪ Name			Change per second

● Item prototype #17
  ▪ Name: 		Rootfs size: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.rootfs.size[{#CONTAINER.NAME}]
  ▪ Type of inf: Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:rootfs
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_rootfs_size_bytes{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #18
  ▪ Name: 		Total system CPU time: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.cpu.time
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		s
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:sys_time
♯ Preprocessing
  ▪ Prometheus pattern: podman_container_cpu_system_seconds_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

Creating a template discovery rule: Trigger prototype

I have created a user macro {$CONTAINER.RUNNING.STATE} on the template with a value of 2, which corresponds to the containers running state. After that, create a trigger prototype to check if the container is in different state other than running.

Template: Podman containers by HTTP and Prometheus; Discovery rule: Container discovery

◘ Trigger prototypes
  ▪ Name:               Container [{#CONTAINER.NAME}] state has changed from running
  ▪ Severity:           Warning
  ▪ Expression:         last(/Podman containers by HTTP and Prometheus/container.state[{#CONTAINER.NAME}])<>{$CONTAINER.RUNNING.STATE}
  ▪ PROBLEM event generation mode: Single
  ▪ OK event closes: All problems

So, once all of this is done, and some container status changes from running and or pod status also changes from running, you will get a problem event.

Fig 10. Generated problem events when the podman pod and container change states.

Technically, I could also create a trigger for container health; however, as all of the received container values for me are -1 (meaning unknown) it makes little sense to make a trigger that will fire right away. You can also add additional item/trigger prototypes in the template. If everything is set up as expected, you should see something like the screenshot below after the LLD rule execution.

Fig 11. Example of the mysql-server container and zabbix pod item values.

Summary

Now, you can monitor both Podman pods and containers using both blog posts of this series. We used the same template item for both the container LLD and item prototypes from the first part of this post.

The post Podman Container Monitoring with Prometheus Exporter, part 2 appeared first on Zabbix Blog.

Podman Container Monitoring with Prometheus Exporter, part 1

Post Syndicated from Janis Eidaks original https://blog.zabbix.com/podman-container-monitoring-with-prometheus-exporter-part-1/30513/

In part one of this blog post, I will show you how to monitor Podman pods using HTTP agent item to retrieve data from the Prometheus Podman exporter. Let’s get started!

Installing and checking Prometheus Podman exporter

First, you will need to install and enable the Prometheus Podman exporter (my OS is CentOS Stream release 9). Then, check that the service is active and running.

# dnf install -y prometheus-podman-exporter

# systemctl enable prometheus-podman-exporter –now

# systemctl status prometheus-podman-exporter

You can check that you are getting the data from the exporter with either the curl command from the machine/VM where the Prometheus podman exporter is installed and started:

# curl http://localhost:9882/metrics
Fig 1. Output of Prometheus podman exporter in CLI

Or through the browser (replace abc with the machine’s IP/DNS ): abc:9882/metrics.

Fig 2. Output of Prometheus Podman exporter in browser

A line starting with # is a comment and contains an explanation regarding the metric; in this case, podman_container_block_input_total will return data in bytes.  In Figure 2, after the comments, you can see several podman_container_block_input_total metrics, one for each container, with different container IDs, pod IDs, and pod names listed in each metric. The metric’s value is displayed on the right side after curly brackets.

Creating a template and template items

Next, I will create a template Podman containers by HTTP and Prometheus where I will put all of the entities (everything will be created on the template). In the template, I will create an item Podman info, which will gather all of the necessary data at defined intervals. This approach will be convenient from a data collection standpoint as the same item data will be used for LLD and item prototypes. During testing, you can set “History” to store data for some time, and when everything is working as expected, then set “History” not to keep any data. This item will be used for the Low-Level Discovery rule and the item prototype.

The item Podman info parameters are as follows:

Template: Podman containers by HTTP and Prometheus

○ Item
  ▪ Name:         Podman info
  ▪ Type          HTTP agent
  ▪ Key:          podman.info
  ▪ Type of inf   text
  ▪ URL           http://{HOST.CONN}:9882/metrics
  ▪ Request type  GET
  ▪ Update int.   5m
  ▪ Req status c. 200
  ▪ History       Do not store
◊ Tags
  ▪ Podman:raw


Fig 3. Template item for data gathering

At this moment, this item will contain just raw data, without any preprocessing steps applied. The IP address will be taken from any host interface added to the host. You will get an error message if the host has no interface.

Fig 4. Error on the host with the linked template without any interface

If you do not want to add an interface to the host, you can define a user macro on the template level and use that user macro in the items URL. After adding the template to the host, just modify the user macro value on the host to correct IP/DNS name.

Fig 5. User macro on template
Fig 6. Template item for data gathering with user macro instead of built in macro from host interface

I can also create an item to determine the number of containers created. I can count specific Prometheus pattern occurrences in the master item to determine this. For this, I will use the podman_container_state parameter. Likewise, I could use different parameters, such as podman_container_info, and count the occurrences of such a pattern. The parameters of the item container count:

Template: Podman containers by HTTP and Prometheus

○ Item
  ▪ Name:         Container count
  ▪ Type          Dependent item
  ▪ Key:          container.count
  ▪ Type of inf   Numeric (unsigned)
  ▪ Master item   Podman containers by HTTP and Prometheus: Podman info
◊ Tags
  ▪ Containers:total
♯ Preprocessing
  ▪ Prometheus pattern     podman_container_state     count
Fig 7. Template item preprocessing step for counting the total number of containers

Creating a Discovery rule in template

Next, the LLD rule will be created to discover Podman pods. It will be a dependent LLD rule based on a Podman info item with a preprocessing step to convert the Prometheus pattern data to JSON format. The caveat is that the LLD discovery will be executed as frequently as the data is received for the item. If there are a lot of hosts with such a template, there will be a lot of LLD processes executed, which can put a strain on your Zabbix instance.

To rectify this issue, I will add a preprocessing step: discard unchanged with heartbeat (as there are no dynamic parameters in the extracted pattern, otherwise we would need to filter out dynamically changing information). For LLD discovery, the recommended interval is around 1h. Additionally, LLD macros will be created from selected JSNOPath variables. The parameters of the LLD rule are shown below.

Template: Podman containers by HTTP and Prometheus

▲ Discovery rule
  ▪ Name:                   POD discovery
  ▪ Type                    Dependent item
  ▪ Key:                    training.pod.discovery
  ▪ Master item             Podman containers by HTTP and Prometheus: Podman info
  ▪ Delete lost resources  After 10d
  ▪ Disable lost resources Immediately
♯ Preprocessing
  ▪ Prometheus to JSON     podman_pod_info
  ▪ Discard unchanged with heartbeat 1h
♦ LLD Macros
  ▪ {#POD.ID}              $.labels.id
  ▪ {#POD.NAME}            $.labels.name
Fig 8. Discovery rule: Pod discovery
Fig 9. Discovery rule: Pod discovery preprocessing tab
Fig 10. Discovery rule: Pod discovery LLD macros tab

The block diagram below will show how the data is transformed. First, a preprocessing step is applied to the data to convert the Prometheus pattern to JSON format, as all data for LLD must be supplied in JSON format.

In the example below, the matching queried pattern is returned in JSON format after this preprocessing step.

Fig 11. Discovery rule preprocessing step: Prometheus to JSON with pattern podman_pod_info

After the preprocessing step, we can assign specific JSONPATH values to LLD macros.

Fig 12. Discovery rule LLD macros: assigning relevant JSONPATH to LLD macros

Creating a template Discovery rule: item prototypes

Now that we have discovered the macros we are interested in, the discovered macros can be used for further prototype (ITEM/HOST/TRIGGER) creation. In this example, I am using the same master item for LLD discovery and the dependent item prototypes, because it is convenient for me, and all the information is available in one item. But usually, there are scenarios where you have to use one item’s data for discovery and the data of another item for populating the prototype values.

In this case, I am interested in the pod ID, when the pod was created, the number of containers in the pod, and the state of the pod. Therefore, I will create the item prototypes and use the LLD macro in the name, key, and preprocessing step. Zabbix will cycle through the discovered LLD macro values and create the items based on the prototype by replacing the LLD macro with discovered values. Although you can set matching item prototype names (which will be confusing), you still have to use the LLD macro in the item key so that different item keys are generated – otherwise, you will get an error regarding duplicate keys. The item prototype parameters are given below.

Fig 13. Low-level discovery rule and item prototypes based on the same item.
Template: Podman containers by HTTP and Prometheus; Discovery rule: POD discovery

○ Item prototype #1
  ▪ Name:         POD ID: [{#POD.NAME}]
  ▪ Type          Dependent item
  ▪ Key:          pod.id[{#POD.NAME}]
  ▪ Type of inf   Character
  ▪ Master item   Podman containers by HTTP and Prometheus: Podman info
♦ Tags
  ▪ Metric:ID
  ▪ Pod:{#CONTAINER.NAME}
♯ Preprocessing
  ▪ Prometheus pattern     podman_pod_containers{id="{#POD.ID}"}          label    id

○ Item prototype #2
  ▪ Name:         POD state: {#POD.NAME}
  ▪ Type          Dependent item
  ▪ Key:          pod.state[{#POD.NAME}]
  ▪ Type of inf   Numeric (float)
  ▪ Master item   Podman containers by HTTP and Prometheus: Podman info
  ▪ Value mapping POD state
♦ Tags
  ▪ Metric:state
  ▪ Pod:{#CONTAINER.NAME}
♯ Preprocessing
  ▪ Prometheus pattern     podman_pod_state{id="{#POD.ID}"}      value

○ Item prototype #3
  ▪ Name:         POD created at: [{#POD.NAME}]
  ▪ Type          Dependent item
  ▪ Key:          pod.created[{#POD.NAME}]
  ▪ Type of inf   Numeric (unsigned)
  ▪ Units         unixtime
  ▪ Master item   Podman containers by HTTP and Prometheus: Podman info
♦ Tags
  ▪ Metric:created
  ▪ Pod:{#CONTAINER.NAME}
♯ Preprocessing
  ▪ Prometheus pattern     podman_pod_created_seconds{id="{#POD.ID}"}     value

○ Item prototype #4
  ▪ Name:         POD container count: [{#POD.NAME}]
  ▪ Type          Dependent item
  ▪ Key:          pod.count[{#POD.ID}]
  ▪ Type of inf   Numeric (unsigned)
  ▪ Master item   Podman containers by HTTP and Prometheus: Podman info
♦ Tags
  ▪ Metric:count
  ▪ Pod:{#CONTAINER.NAME}

On the template, I have also created a value map for deciphering the numerical pod state codes to text strings for better clarity.

Fig 14. Value mapping for the POD state item

Here are some screenshots of the POD state item prototype, shown below.

Fig 15. POD state item prototype: item prototype tab
Fig 16. POD state item prototype: tag tab
Fig 17. POD state item prototype: preprocessing tab

Creating a template Discovery rule: trigger prototype

We can also create a trigger prototype to generate an alert if there is something wrong with the pod. I have created a user macro {$POD.RUNNING.STATE} on the template with a value of 4, which corresponds to the running state.

Template: Podman containers by HTTP and Prometheus; Discovery rule: POD discovery

◘ Trigger prototypes:
  ▪ Name:               POD [{#POD.NAME}] state has changed from running
  ▪ Severity:           Warning
  ▪ Expression: last(/Podman containers by HTTP and Prometheus/pod.state[{#POD.NAME}])<>{$POD.RUNNING.STATE}
  ▪ PROBLEM event generation mode: Single
  ▪ OK event closes: All problems
Fig 18. Trigger prototype based on POD state item value

Once you link the template to the host and execute the LLD rule, you should start seeing the Podman pods ( if you have them), similar to the screenshot below.

Fig 19. Latest data for the host with the linked template

Summary

This blog post shows how to get data with HTTP agent from Prometheus Podman exporter and use the same item data for the Discovery rule as well as item and trigger prototypes. Check out part 2 of this series to find out how to discover and monitor Podman containers.

The post Podman Container Monitoring with Prometheus Exporter, part 1 appeared first on Zabbix Blog.

Next-Level Alert Analysis with DeepSeek and Zabbix

Post Syndicated from Zhe Cheng original https://blog.zabbix.com/next-level-alert-analysis-with-deepseek-and-zabbix/30424/

As IT infrastructures grow increasingly complex, efficiently analyzing monitoring data and accelerating incident response have become critical challenges for operations teams. This post explores a few innovative applications of DeepSeek when integrated with Zabbix.

Requirements:

– Zabbix server 7.0 or higher
– DeepSeek API (Alternatively, other AI APIs can be used if needed)

1. Scenario One: One-Click Intelligent Alert Analysis

By integrating DeepSeek Analytics into the Zabbix frontend, users can conduct intelligent alert analysis with just one click. This integration facilitates the swift generation of comprehensive fault analyses and solution suggestions, markedly decreasing the MTTR (Mean Time to Resolution). Consequently, it streamlines the troubleshooting process, alleviates the workload on IT personnel, ensures system stability, and conserves both time and resources.

1.1  On the Zabbix home page, navigate to “Alerts” > “Scripts”, and click on the “Create script” button.

1.2  Configuration script:

  • Name: Can be customized
  • Scope: Select “Manual event action”
  • Menu path: Customize menu paths for quick access
  • Type: Select “Script”
  • Execute on: Select “Zabbix proxy or server”

1.3 Enter the following command in the command bar:

/etc/zabbix/scripts/send_alert_to_ai.sh "{TRIGGER.NAME}" "{TRIGGER.SUBJECT}"  "{HOST.NAME}" "{HOST.IP}" "{EVENT.TIME}" "{TRIGGER.SEVERITY}"

1.4  Create an API call script on zabbix-server.

1.4.1 Modify the Zabbix Server Configuration File and Enable Global Scripts:

Open the Zabbix server configuration file for editing:

vi /etc/zabbix/zabbix_server.conf

Set the EnableGlobalScripts option to 1:

EnableGlobalScripts=1

Save the changes and exit the editor. Then, restart the Zabbix server service to apply the changes:

systemctl restart zabbix-server

1.4.2 Create an API Call Script.

Create a directory for custom scripts if it does not already exist:

mkdir -p /etc/zabbix/scripts && cd /etc/zabbix/scripts

Note: If the frontend prompts that the script file cannot be found, try moving the script to the directory used by the Nginx agent. Create a new script file named send_alert_to_ai.sh:

vi send_alert_to_ai.sh

Add the following content to the script, replacing DeepSeek KEY with your actual API key. Make sure you adjust the API call method if using a different AI service:

#!/bin/bash

# DeepSeek API configuration
API_URL="https://api.deepseek.com/chat/completions"
API_KEY="xxxxxxxxxxxxxxxxxxxx"

# Obtain the parameters to be passed as alarm information
TRIGGER_NAME="$1"
ALERT_SUBJECT="$2"
HOSTNAME="$3"
HOST_IP="$4"
EVENT_TIME="$5"
TRIGGER_SEVERITY="$6"

# Build a more concise JSON format for alarm information
alert_info=$(cat <<EOF
{
"model": "deepseek-chat",
"messages": [
{"role": "system", "content": "You are an assistant focused on responding quickly to system alarms。"},
{"role": "user", "content": "The following alarm information is received:\n\n: $TRIGGER_NAME\n: $ALERT_SUBJECT\n: $HOSTNAME\n: $HOST_IP\n: $EVENT_TIME\n: $TRIGGER_SEVERITY\n\nPlease tell me the cause of the alarm and the handling measures in a short and professional language with a word limit of 300 words。"}
],
"stream": false
}
EOF
)

# Send the POST request and capture the response and HTTP status code
response=$(curl -s -w "\n%{http_code}" -X POST "$API_URL" \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $API_KEY" \
-d "$alert_info")

# Separate HTTP status codes from response bodies
http_code=$(echo "$response" | tail -n1)
response_body=$(echo "$response" | sed '$d')

# Parse and extract the content field
if [ "$http_code" -eq 200 ]; then
# Parse JSON using the jq tool
if ! command -v jq &> /dev/null; then
echo "jq could not be found, please install it first."
exit 1
fi

# Extract the content field and format the output
content=$(echo "$response_body" | jq -r '.choices[0].message.content')
echo -e "Analysis result:\n$content"
else
echo "failure: HTTP status code $http_code, respond: $response_body"
fi

Make the script executable:

chmod +x send_alert_to_ai.sh

Note: The script provided invokes the official DeepSeek API. Replace DeepSeek KEY with your actual API_KEY. If you are using another AI service, please confirm the appropriate API invocation method.

Important Notes:

Note: The script relies on jq to process and parse JSON data for tasks such as filtering, mapping, aggregating, and formatting. If jq is not installed on your system, follow these instructions to install it.

For Debian/Ubuntu Systems:

apt-get update
apt-get install jq

For CentOS/RHEL Systems:

yum install epel-release
yum install jq

1.5 Actual Effect Display:

1.6  Optional Optimization Items.

1.6.1 Adjust Output Box Size for Better Browsing.

After executing the script, you may find that the output box is too small and inconvenient to browse. To optimize this, you can modify the front-end CSS file as follows.

Back up the existing CSS File:

cd /usr/share/nginx/html/assets/styles/
cp blue-theme.css blue-theme.css.bak

Edit the CSS File:

vi /usr/share/nginx/html/assets/styles/blue-theme.css

Add Custom Styles at the End of the File.

Add the following CSS rules to adjust the size and behavior of the output box:

#execution-output {
height: 500px; /* Adjust to your desired height */
width: 540px; /* Optional: Adjust the width as required */
overflow-y: auto; /* Displays scrollbar when content exceeds the set height */
}

Save and exit the editor. At this point, clear the browser cache and reload the page to see the changes take effect.

1.6.2 How to Optimize Slow Output Response after Executing the One-Click Analysis Script.

During actual testing, it was estimated that returning a 300-word result takes approximately 20 to 30 seconds. While you can improve the response speed by adjusting the preset prompt words in the script, this approach may reduce the richness of the analysis content. Therefore, it is recommended to balance speed and content depth by adjusting the number of replies in the script’s prompt words according to your actual needs.

Actual effect display:

2. Scenario Two: Zabbix Documentation Knowledge Base Assistant

In today’s fast-paced IT environment, managing and retrieving information efficiently is crucial. To address this need, we’ve developed the Zabbix KB Assistant, an intelligent knowledge base solution built on MaxKB—an open-source Q&A system leveraging large language models.

This assistant streamlines access to Zabbix’s extensive documentation, making it easier than ever for users to find the information they require.
MaxKB stands out for its seamless integration capabilities, allowing for quick uploads of documents and automatic crawling of online content.

Its flexibility means it can be effortlessly embedded into third-party systems, including our very own Zabbix platform. The project is available at the GitHub repository.

The development process of Zabbix KB Assistant involved configuring MaxKB to recognize and parse the official Zabbix documentation. By utilizing this URL, we ensured that the latest updates and comprehensive guides are always accessible within our assistant. After setting up the core model configurations, we created a dedicated knowledge base tailored to Zabbix’s rich content.

With the knowledge base in place, we proceeded to integrate Zabbix KB Assistant into the Zabbix frontend. This step was essential for providing instant access to users navigating the Zabbix interface. By embedding a floating window mode, users can interact with the assistant without leaving their current page—a feature that significantly enhances user experience.

Actual effect display:

3. Scenario Three: DingTalk Alert Enhancement

By integrating DeepSeek’s deep analysis capabilities, DingTalk can automatically analyze alarm information upon receiving alerts. This integration provides precise fault diagnosis and solutions, aiding IT operations and maintenance personnel in quickly identifying and resolving issues. Consequently, this improves the efficiency of system maintenance and reduces downtime.

3.1 Create a Bot and Configure Security Settings.

First, create a new bot within the DingTalk group and ensure that the keyword “Alarm” is properly configured in the security settings. Next, retrieve the webhook URL for this bot and keep it safe for later use.

3.2 Install Python3 and Necessary Libraries.

Ensure that Python3 along with the required libraries are installed on your system. Depending on your operating system, follow these instructions.

For Ubuntu/Debian systems:

sudo apt update
sudo apt install python3 python3-pip
pip3 install requests

For CentOS/RHEL systems:

sudo dnf install python3
pip3 install requests

3.3 Below is an example script (deepseekdingding.py) located at /usr/lib/zabbix/alertscripts/.

Replace the placeholder webhook URL and DeepSeek API key in the script with your actual values:

#!/usr/bin/env python3
#coding:utf-8
import requests
import sys
import json

class DingTalkBot(object):
    # Send an alarm
    def send_news_message(self, webhook_url, subject, content, ai_response):
        url = webhook_url
        data = {
            "msgtype": "markdown",
            "markdown": {
                "title": subject,
                "text": f"{subject}\n{content}\n\n【DeepSeek analysis】:\n\n{ai_response}"  
            }
        }
        headers = {'Content-Type': 'application/json'}
        response = requests.post(url, headers=headers, data=json.dumps(data))
        return response

if __name__ == '__main__':
    WEBHOOK_URL = 'https://oapi.dingtalk.com/robot/send?access_token=224c1ff0c6df60a809b3c5b69b8448486b780d292e9d395ac8fbf84980214e30'  # Webhook
    API_URL = 'https://api.deepseek.com/chat/completions'
    API_KEY = "xxxxxxxxxxxxxxxxxxxx"  # DeepSeek API

    if len(sys.argv) < 3:
        print("Error: Not enough arguments provided.")
        sys.exit(1)

    subject = str(sys.argv[1])  
    content = str(sys.argv[2])  

    print(f"Received subject: {subject}")
    print(f"Received content: {content}")

    try:
        headers = {
            'Authorization': f'Bearer {API_KEY}',
            'Content-Type': 'application/json',
        }
        payload = {
            "model": "deepseek-chat",  # DeepSeek
            "messages": [
                {"role": "user", "content": f"If you are a professional IT operation and maintenance expert, please tell me the cause of these alarms and handling suggestions in a concise and professional language with a word limit of 100 words{content}"}
            ]
        }
        ai_response = requests.post(API_URL, headers=headers, json=payload)
        ai_response.raise_for_status()  
        ai_response_content = ai_response.json().get('choices', [{}])[0].get('message', {}).get('content', '')
    except Exception as e:
        ai_response_content = "\nThe interface call timed out or an error occurred. Please check the configuration and try again"

    bot = DingTalkBot()
    response = bot.send_news_message(WEBHOOK_URL, subject, content, ai_response_content)

    if response.status_code == 200:
        print("successfully")
    else:
        print(f"failed: {response.text}")

3.5 On the Zabbix home page, go to Alerts – Media types – Create Media type and then enter the following information:

  • Name: aiAlarm-Dingtalk
  • Type: script
  • Script name: deepseekdingding.py
  • Script parameter: {ALERT.MESSAGE} {ALERT.SUBJECT}

3.6 Create an alarm action.

Go to Alarm – Action – Trigger actions – Create action and set the name to Alarm -deepseek. Select this parameter as required:

Edit the action options as follows:

Send to media type aiAlarm-Dingtalk
Topic fault alarm: {EVENT.NAME}
message
【Zabbix Alarm Notification 】

Alarm group: {TRIGGER.HOSTGROUP.NAME}

Alarm host: {HOSTNAME1}

Alarm time: {EVENT.DATE} {EVENT.TIME}

Alert level: {TRIGGER.SEVERITY}

Problem information: {TRIGGER.NAME}

Confirm the update.

3.7 Configure notification rights for users.

The following item is added to the “User-User-Alarm” media dialog box. Once added, click Update.

Actual effect display:

4. Scenario Four: One-Click System Service Deep Analysis

Our solution integrates DeepSeek analysis to offer a one-click intelligent inspection tool that automates the collection of service configurations, logs, and status from within your system. This information is then sent via API to DeepSeek for comprehensive analysis.

Our approach begins by extracting relevant configuration data, recent log entries, and current service statuses. These pieces of information are combined with predefined prompts and submitted to DeepSeek through its API. For instance, a prompt might look like this:

“Here are the current logs for XXX service:\n\n${recent_logs}\n\nService. Status is as follows:\n${service_status}\n. Please analyze the following four aspects based on this information and provide a concise report within 500 words: service status analysis, configuration review, historical issue examination, and troubleshooting recommendations.”

DeepSeek processes this input to perform a detailed breakdown across these four areas, delivering structured feedback and actionable insights.
This integration offers deep system analysis and precise optimization suggestions, enabling swift responses to system changes or anomalies. It aids administrators in promptly identifying and addressing issues.

In addition, it’s easily integrated into existing monitoring systems, allowing adjustments to the depth and scope of analysis as needed. The solution boasts high scalability and flexibility, catering to evolving business requirements.

Actual effect display :

The post Next-Level Alert Analysis with DeepSeek and Zabbix appeared first on Zabbix Blog.

Build a Culture of Monitoring and Get Buy-In with Zabbix

Post Syndicated from Michael Kammer original https://blog.zabbix.com/build-a-culture-of-monitoring-and-get-buy-in-with-zabbix/30085/

In today’s fast-paced, interconnected IT world, simply waiting for something to fail before fixing it isn’t good enough. A proactive approach to monitoring, which aims to identify and address potential issues before they escalate into major disruptions, is a necessity rather than a luxury.

Here at Zabbix, we’ve got plenty of reason to believe that we offer the most flexible monitoring solution available on the market today. However, choosing the best monitoring tool for your organization’s needs is only half the battle – you also need to get buy-in from team members who may not understand the need for monitoring, may be fearful of and resistant to change, and may not be familiar with the technologies behind monitoring.

In this post, we’ll take a look at a few strategies you can use to help win over lukewarm or hesitant colleagues and build a culture of monitoring. We’ll also explore how choosing Zabbix for your monitoring needs can make each strategy a bit easier to implement.

Strategy 1: Explain the “why”

One of the first questions that you can anticipate during any change initiative is simply, “what for?” The ethos of “don’t fix what isn’t broken” runs strong in the tech community, and unless you go above and beyond to explain why monitoring matters, your team will remain skeptical.

Zabbix can help you make your case by providing you with the evidence you need to bolster your case. We’ve got plenty of testimonials available from tech communities worldwide (including PeerSpot, Gartner, and Capterra), and no matter what field you’re in or how big your team is, we’ve most likely got a case study or two available that shows how monitoring with Zabbix was a game changer for a company like yours.

All of this should help you explain the rationale for the change in an open and transparent way. When it comes to monitoring, sharing details on costs, expected benefits, and what will happen if no change is made will build understanding around why monitoring is necessary and why monitoring with Zabbix is the right answer for your team’s needs.

Strategy 2: Show your team what’s in it for them

One of the most effective ways to get employee buy-in for monitoring is by highlighting the benefits it will bring to individual employees. Show how monitoring can simplify their tasks, improve efficiency, and enhance their work experience, and give them concrete examples of how the technology can make their jobs easier or help them to deliver better results.

We recently had a large managed services provider (MSP) use our monitoring solution as a true “force multiplier”, allowing them to monitor their systems, automate tasks based on real-time events, and provide immediate responses to issues without manual intervention. Thanks to Zabbix, their engineers report higher job satisfaction thanks to no longer having to be “on call” at all hours to solve simple issues, while management has seen productivity skyrocket thanks to their team’s newfound ability to find potential issues before they become real problems.

Strategy 3: Turn important stakeholders into monitoring champions

Determine who monitoring will impact and who needs to be kept informed. This might be team leaders, IT staff, end users, and/or an executive sponsor. Getting input from these groups early on will help you anticipate needs and concerns, and you’ll also want to identify influential employees who are enthusiastic about monitoring and get them to help you promote it.

A great way to help them do so is by encouraging them to attend one (or more) Zabbix events – we’ve got free meetings, online meetups, regional conferences, or even our yearly Summit in Latvia. No matter where you happen to be located, there’s a pretty good chance that we’ll soon be bringing your key people a chance to network with like-minded professionals from multiple industries, expand their knowledge, get answers to their questions, and explore how Zabbix can work for them.

Strategy 4: Provide adequate training

Equipping employees with the skills and knowledge they need to get the most out of a monitoring system means gaining a solid understanding of their current capabilities and then finding out which gaps you most urgently need to fill. Chances are, you’ll need to provide guidance, documentation, hands-on demonstrations, and access to experts – and this is another area where Zabbix has you covered.

Zabbix Certified trainings are designed to help your people learn Zabbix inside and out, giving them the practical knowledge they’ll need to increase their productivity and performance. When you explore our training options, you’ll find a wide variety of courses, everything from one-day sessions that cover the basics to week-long sessions that guarantee users the ability to tackle any Zabbix challenge on their own.

In addition, we’ve got plenty of other free resources available to teams and individuals looking to upskill, including our famously active forum, blog, webinars, and newsletter.

Conclusion

Building a culture of monitoring requires commitment from every level of an organization. By choosing Zabbix as the guide to your monitoring journey and following the strategies outlined in this article, you and your team can successfully implement and maintain a robust monitoring strategy that will help you achieve your organization’s IT goals.

To learn more about what Zabbix can do for you, visit our website.

The post Build a Culture of Monitoring and Get Buy-In with Zabbix appeared first on Zabbix Blog.

Monitor Your Wi-Fi Signal Strength with Zabbix

Post Syndicated from Janne Pikkarainen original https://blog.zabbix.com/monitor-your-wi-fi-signal-strength-with-zabbix/29835/

Can you monitor the signal strength of different Wi-Fi devices that are connected to your (home) router with Zabbix? Of course you can! This is a really quick post that also shows how ChatGPT or any LLM can boost your productivity when doing this kind of thing.

I have an ASUS RT-AX68U router running on Asuswrt-Merlin firmware. On its web interface, it can show you all kinds of details about your network and the devices on it. This is nice, but it would be even nicer to add some of that to Zabbix. One interesting idea for me would be to monitor the signal strength of my Wi-FI devices around the house, so let’s do that and start monitoring RSSI!

What’s RSSI?

Here’s a reply by ChatGPT:

In Wi-Fi (and RF in general), RSSI (Received Signal Strength Indicator) is typically measured in negative dBm values:

• The closer the value is to 0 dBm, the stronger (better) the signal.

• The more negative the value, the weaker the signal.

Broadly speaking, here is a rough guideline:

• -30 dBm: Extremely strong signal (almost too strong – rare in normal conditions).

• -50 dBm: Excellent signal.

• -60 dBm: Very good signal, plenty strong for most uses.

• -70 dBm: Adequate; connectivity is usually reliable but might slow at times.

• -80 dBm: Marginal; still connected but performance may degrade.

• -90 dBm or lower: Very weak; likely to drop connection or have very poor speeds.

Monitoring implementation

If you are a regular reader, you should know by now that I’m not a fan of letting Zabbix agent or any other agent run commands directly for gathering metrics unless I really need the metrics that second. Rather, I’ll use cron jobs or any other background way of creating text files which then will be parsed by Zabbix.

That said, my ASUS now runs a shell script every minute, which then writes a text file /tmp/rssi.txt, which is read by Zabbix agent.

The shell script

Thank you ChatGPT for the following: The script uses wl -i assoclist command to list the connected devices with their MAC addresses and signal strength, and converts those MAC addresses to hostnames to be human-readable.

#!/bin/sh

# Interfaces for 2.4 and 5 GHz (adjust if your router uses different names)
IFACES="eth5 eth6"

LEASES_FILE="/var/lib/misc/dnsmasq.leases"
rm -f /tmp/rssi.txt

echo "Hostname:RSSI" >/tmp/rssi.txt
for iface in $IFACES
do
# List all MACs associated on this interface
for MAC in $(wl -i "$iface" assoclist 2>/dev/null | awk '{print $2}')
do
# Get RSSI
RSSI=$(wl -i "$iface" rssi "$MAC" 2>/dev/null)

# Look up IP and hostname in dnsmasq leases (if present)
# The leases file format is: <epoch> <MAC> <IP> <hostname> <clientid>
IP=$(grep -i "$MAC" "$LEASES_FILE" | awk '{print $3}')
HOSTNAME=$(grep -i "$MAC" "$LEASES_FILE" | awk '{print $4}')

# If the device is static or not found in dnsmasq leases, IP/HOSTNAME might be empty
# so handle that gracefully
[ -z "$IP" ] && IP="Unknown"
[ -z "$HOSTNAME" ] && HOSTNAME="Unknown"

#echo "MAC $MAC:"
#echo " RSSI: $RSSI dBm"
#echo " IP: $IP"
#echo " Hostname: $HOSTNAME"
echo "$HOSTNAME:$RSSI" >>/tmp/rssi.txt
done
done

It outputs this, with self-explanatory results.

Hostname:RSSI
Watch:-43
058743599:-66
Samsung:-62
SonosZP:-45
BroadLink_OEM-T1-89-d3-bb:-57
Kitchen:-52
Mac:-39
iPhone:-40
*:-60
MacBookPro:-43

Adding it to Zabbix

First, I added a new template, for which I then added a new master item reading the /tmp/rssi.txt file.

Because ChatGPT script did make the output in CSV format with : as delimiter, we can use Zabbix item preprocessing to convert that CSV to JSON. The JSON output looks like this.

[{"Hostname":"Watch","RSSI":"-45"},{"Hostname":"058743599","RSSI":"-70"},{"Hostname":"Samsung","RSSI":"-60"},{"Hostname":"SonosZP","RSSI":"-44"},{"Hostname":"BroadLink_OEM-T1-89-d3-bb","RSSI":"-61"},{"Hostname":"Kitchen","RSSI":"-53"},{"Hostname":"Mac","RSSI":"-37"},{"Hostname":"iPhone","RSSI":"-39"},{"Hostname":"*","RSSI":"-56"},{"Hostname":"MacBookPro","RSSI":"-41"}]

With this, we can then use Zabbix low-level discovery to automatically create the items.

Discovery rule

Now that we have our master item, let’s add the discovery rule, which can go through the JSON. The discovery rule uses my previous item as a dependent item, from which it can parse everything in one go.

Discovery item prototype

In item prototype, let’s make it again use the raw list as a dependent item and go from there.

Then in preprocessing, it picks the RSSI value for whatever device LLD was going through by using a JSONPath query…

…or as text:

$[?(@.Hostname=='{#WIFICLIENT}’)].RSSI.first()

That’s pretty much it!

We now have the data coming in once per minute:

Here’s a little dashboard, too. It shows you the traditional bar that’s available on the Top hosts/items widget, and also the new Sparkline that’s on Zabbix 7.2.

Bonus: Location estimation

After a little bit of walking around and observing the devices, I added some value mapping to make Zabbix estimate where the devices would be located. It’s not so useful for static objects, but when I move around with my Apple Watch and iPhone, I could make an attempt to monitor my location at home, too.

After this fine-tuning, my dashboard now looks like this:

Thanks for reading, and have fun conducting your own experiments!

The post Monitor Your Wi-Fi Signal Strength with Zabbix appeared first on Zabbix Blog.

Monitoring Pure Storage FlashArray with Zabbix

Post Syndicated from Aleksandr Iantsen original https://blog.zabbix.com/monitoring-pure-storage-flasharray-with-zabbix/29752/

Monitoring data storage systems is the key to keeping modern IT systems running smoothly. With the rapid growth of data and the need for instant access, using high-performance solutions like Pure Storage FlashArray is not just an advantage – it’s a necessity. However, even the most advanced systems require careful oversight regarding their performance and health. Good monitoring helps find problems early and makes it possible to use resources more efficiently. In this article, we will explore how to set up monitoring for the Pure Storage FlashArray storage system with Zabbix using our new templates.

Pure Storage FlashArray offers two API versions: REST API 1.X and REST API 2.X. To ensure compatibility and comprehensive coverage for the maximum number of devices, two templates have been developed for these API versions. This allows users to effectively monitor their Pure Storage FlashArray storage systems regardless of which API version they are utilizing, making sure that they can take full advantage of the monitoring capabilities and performance metrics provided by each version. By accommodating both API versions, organizations can achieve a more flexible and comprehensive monitoring setup tailored to meet their specific infrastructure needs.

Preparing Pure Storage FlashArray for monitoring with Zabbix

In all of these examples, the Purity for FlashArray (Purity//FA) graphical user interface (GUI) will be used, so keep in mind that some of the UI elements or navigation menus can potentially change in the future.

User creation

First of all, you need to set up a user in GUI that Zabbix will use to access the REST API and gather data. To do so, navigate to 'Settings' -> 'Users and Policies' -> 'Users' from the left-side menu. On this page, pay attention to the ‘Users’ block. In the upper right corner of this block, you will see three dots. Click on them to open a context menu. In this menu, select the 'Create User...' option. Here, create a new user by filling in the fields.


API Key creation

Unlike Pure Storage FlashArray v2 by HTTP, Pure Storage FlashArray v1 by HTTP supports authentication using a username and password instead of a token. This feature is left for backward compatibility with older versions of devices and firmware. However, it is strongly recommended to use token authentication if there are no technical limitations.

If you do plan to use username and password authentication in the Pure Storage FlashArray v1 by HTTP template, you can skip this step and move on to the next one.

Once you have created the user, the next step is to generate an API token. To do this, find the newly created user in the 'Users' block on the 'Settings' -> 'Users and Policies' page. On the right side of the user’s entry, locate the three dots and click on them to open the menu. From this menu, select 'Create API Token...'. Follow the prompts to generate the API token, which Zabbix will use to authenticate requests. The 'Expires In' field can be left empty.


After clicking the Create button,  the GUI will show you details about the API key. Save this information somewhere safe for now, as we will need to use this data later in Zabbix. After saving, you can close this pop-up.

Preparing Zabbix

Create a host

Open your Zabbix web interface, then navigate to the ‘Configuration' -> 'Hosts‘ page and create a new host. In this step, you need to specify a host name of your choice, so choose one of the Pure Storage FlashArray v1 by HTTP or Pure Storage FlashArray v2 by HTTP templates and assign the host to a group. The choice of template depends on the version of the Pure Storage FlashArray RESTful API that is supported by your devices.


Before clicking the Add button, you need to configure macros. Open the Macros tab and choose both Inherited and host macros. You’ll find a lot of macros there, but only a few of them need to be changed to start using the template. Let’s take a look at these macros.

Macro list in the Pure Storage FlashArray v1 by HTTP template:

Macro Default value Description
{$PURE.FLASHARRAY.API.URL} Web interface URL.
{$PURE.FLASHARRAY.API.TOKEN} API token.
{$PURE.FLASHARRAY.API.USERNAME} Web interface username.
{$PURE.FLASHARRAY.API.PASSWORD} Web interface password.
{$PURE.FLASHARRAY.API.VERSION} 1.19 API version.

For the Pure Storage FlashArray v1 by HTTP template, it is mandatory to specify the {$PURE.FLASHARRAY.API.URL} macro, as well as either the {$PURE.FLASHARRAY.API.TOKEN} or {$PURE.FLASHARRAY.API.USERNAME} and {$PURE.FLASHARRAY.API.PASSWORD}. It is highly recommended to use a token for authentication.

Macro list in the Pure Storage FlashArray v2 by HTTP template:

Macro Default value Description
{$PURE.FLASHARRAY.API.URL} Web interface URL.
{$PURE.FLASHARRAY.API.TOKEN} API token.
{$PURE.FLASHARRAY.API.VERSION} 2.36 API version.

For the Pure Storage FlashArray v2 by HTTP template, it is mandatory to specify just the {$PURE.FLASHARRAY.API.URL} and {$PURE.FLASHARRAY.API.TOKEN} macros to start using the template.

You can change the value for the {$PURE.FLASHARRAY.API.VERSION} macro if your device does not support this version of the API.

After specifying at least the mandatory macro values, your Macros tab should look something like this:


After clicking the Add button, this host will be added to Zabbix.

Data collection

After following the above steps, you should notice the newly created triggers and items after a short time if the macro values are correct.

In case there are any problems with the template’s data collection, you will find errors in the last history data of items with a name ending with item errors. Also, the corresponding triggers should be fired if there are any problems with the collection of any data.

After that, you should see newly discovered items in the Items view (for example).


On top of that, each host will have its own dashboard created automatically that will provide you with a good overview of resource utilization.


Use macros for low-level discovery filtering

In official Zabbix templates, you might find macros that end with MATCHES and NOT_MATCHES. These are used for low-level discovery rules (LLDs), to help you filter resources that should or should not be discovered. These values use regular expressions. Therefore, you can use wildcard symbols for pattern matching.

Usage of these macros can be found in the Filters tab, under discovery rules.

The typical default value for MATCHES is .* and for NOT_MATCHES – CHANGE_IF_NEEDED. This means that any kind of value will be discovered if it is not equal to CHANGE_IF_NEEDED. For example, in Network interface discovery, filters are used to check the interface name:

  • Macro {$PURE.FLASHARRAY.NETIF.LLD.FILTER.NAME.MATCHES} has a value of .*;
  • Macro {$PURE.FLASHARRAY.NETIF.LLD.FILTER.NAME.NOT_MATCHES} has a value of CHANGE_IF_NEEDED.

You can set the value of macro {$PURE.FLASHARRAY.NETIF.LLD.FILTER.NAME.NOT_MATCHES} to filevip, which will cause an interface named filevip to not be discovered.

Now that you have an idea how these filters work, you can adjust them based on your requirements.

HTTP proxy usage

If needed, you can specify an HTTP proxy for the template to use by changing the value of the{$PURE.FLASHARRAY.HTTP_PROXY} user macro. Every request will use this proxy.

Afterword

To wrap things up, setting up monitoring for Pure Storage FlashArray devices in Zabbix is an important step that guarantees the smooth operation of your infrastructure. I hope that our new templates will help you manage and monitor your devices more effectively.

This short article has been created to provide you with the necessary knowledge and tools to set up a monitoring system that meets your specific needs. By enabling efficient monitoring, you will be better equipped to respond to changes in system performance and maintain optimal operation. I believe this material will be valuable in helping you achieve these goals! 

The post Monitoring Pure Storage FlashArray with Zabbix appeared first on Zabbix Blog.

Building a Monitoring Dashboard: Which Metrics to Track?

Post Syndicated from Michael Kammer original https://blog.zabbix.com/building-a-monitoring-dashboard-which-metrics-to-track/29777/

A well-designed monitoring dashboard is the key to helping users process, interact with, and analyze data. Done right, it allows key decision-makers to track metrics and gain insights in an organized, easy-to-read format, while giving technical teams complete visibility into IT performance at a single glance. Done wrong, it creates information overload, with too much of everything – too many graphs, colors, widgets, and other sources of information, making it at best deceptive and at worst completely useless.

Obviously, there’s no dashboard big enough to display every possible metric for every possible stakeholder, which is why the key to making a well-organized, informative dashboard that doesn’t confuse the viewer is knowing which metrics to track. By sticking to the absolute “must haves,” you’ll make sure that users can find mission-critical information first. But how should you choose which metrics to track? We’ve put our hard-won dashboard expertise to work and identified four key metric groups that no dashboard should be considered complete without.

Global metrics

System uptime and availability. Availability is one of the most important metrics you can use to determine your network’s performance, because it’s a metric that everyone can see the effects of immediately. For a business, it’s critical when it comes to making sure that the services provided to users are consistently available.

Overall resource utilization (CPU, memory, disk storage, etc.). Think of tracking resource utilization like keeping tabs on your phone’s battery life. You need to track CPU, memory, disk storage, and network usage to keep everything running smoothly. Keeping an eye on those metrics will help you fix small issues before they turn into gigantic problems.

Top critical issues or alerts. Speaking of problems, they can and will happen – and when they do, you’ll naturally want to know about them as soon as possible. An alert can be as simple as a notification of a system update, or it can draw attention to an unusual spike in errors. It could also call attention to a major emergency that demands immediate attention. Either way, no effective dashboard is complete without them.

SLA compliance status. If you’re running a business, monitoring SLA compliance status lets you see service availability and performance, which in turn guarantee customer satisfaction. It allows for quick detection of issues, making proactive management and resolution possible before customers feel any impact.

Infrastructure metrics

Server performance (CPU, RAM, disk I/O). Tracking the response time, central processing unit (CPU) utilization, memory consumption, and network bandwidth of a server helps guarantee a functional user experience. It involves keeping an eye on CPU and RAM utilization, disk I/O (input and output operations involving a physical disk), plus a variety of other sub-metrics.

Application health. Monitoring application health involves collecting, analyzing, and interpreting data about an application’s performance, availability, and behavior. It’s mission-critical because it can help you detect and troubleshoot problems, optimize resource utilization, and provide the application’s users with the quality experience they expect.

Storage usage and trends. Keeping track of storage usage on your dashboard gives you a real-time view of storage metrics as well as predictive analytics (useful for capacity planning) and proactive issue detection, across on-premise and cloud storage environments. Like so many other monitored metrics, its purpose is to maintain optimal storage performance while preventing potential issues before they impact any business operations.

Database performance metrics. Basically, database monitoring is how you measure what you want to improve. It’s what you do before you start performance tuning. Keeping track of your database on your dashboard makes this possible by collecting performance metrics, so that you’re always aware of whether your database can fully support your applications and respond quickly to queries.

Network metrics

Bandwidth utilization and traffic patterns. Bandwidth refers to the maximum data transmission rate on a network at a particular time. Having this metric on your dashboard will let you easily track the amount of bandwidth your network is using and make you immediately aware if you run over the bandwidth threshold.

Latency and packet loss. Latency, or network delay, is a network performance metric that measures the amount of time it takes to transfer data from one destination to another. Consistent delays or unusual spikes in delay time usually mean that you have a major network performance issue. Tracking latency and packet loss on your dashboard will let you know if data transfers are taking too long, while also helping you make sure that any lost data packets get to their destinations.

Interface status and error rates. A network interface can be either networking hardware or a software interface. Monitoring them on your dashboard lets you see each and every network device, and tracking their performance is important when it comes time to identify the root causes of poor performance and network bottlenecks.

Firewall and VPN tunnel status. Monitoring the status of Firewalls and VPN tunnels is important because (among other things) it keeps you aware of whether your VPN tunnel interface is up and available for passing traffic, and whether the destination IP address being monitored is reachable. At the same time, you’ll also have access to real-time information about how your firewall is working, which will keep you aware of any security holes or incorrect settings before they become major problems.

Security metrics

Unauthorized access attempts. Unauthorized access is a big risk to businesses, jeopardizing sensitive data and disrupting operations. You can track attempts by unauthorized users to gain access to any website, server, device, or app by monitoring user activity on your dashboard. This data can also be labeled and sorted so that you can easily interpret it at a glance.

Endpoint security status (AV, patching). Endpoints are basically any devices that connect to networks, including laptops, mobile phones, and IoT devices. The more of them you have, the greater your chances of data loss and cyber threat entry. Monitoring the critical junctures of endpoints on your dashboard will help you identify and prevent threats while making sure that you have quick response measures in place to protect your data and systems.

Compliance and audit logs. Compliance and audit logs are there to make sure errors are noticed and fixed, keep you compliant with regulatory requirements, improve business security, and detect fraud. Monitor them on your dashboard, and you’ll have real-time visibility into your compliance posture as well as immediate alerts when a potential violation is detected.

Active security alerts or anomalies. Continuously keeping an eye on your systems and network lets you detect threats (anything from malware to abnormal activities and unauthorized access) before they escalate and cause real damage. In turn, this helps you maintain user trust, avoid downtime, and comply with data security regulations.

These metrics should give any dashboard a solid foundation that can be easily customized to meet specific business or operational goals.

The Zabbix Advantage

One of Zabbix’s most important features has always been our easily customizable dashboards, which allow users to see and analyze even the most complex monitoring data at a single glance. When it’s time to keep tabs on the essential metrics we identified above, Zabbix dashboards allow anyone (or any infrastructure team) to efficiently monitor network performance, manage resource usage, and guarantee device/application availability.

Zabbix’s graphing and visualization features make it easy to see historical trends and make comparisons. You can choose whatever visualization format is best for a particular set of data, including line graphs, bar charts, pie charts, gauges, and more. Not only that, Zabbix dashboard widgets can communicate with each other, serve as data sources for other widgets, and dynamically update the information they display based on the data source.

To learn more about the flexibility of Zabbix dashboards and see how they can help you track just about any metric imaginable, contact us.

The post Building a Monitoring Dashboard: Which Metrics to Track? appeared first on Zabbix Blog.

Searching for the cause of hung tasks in the Linux kernel

Post Syndicated from Oxana Kharitonova original https://blog.cloudflare.com/searching-for-the-cause-of-hung-tasks-in-the-linux-kernel/

Depending on your configuration, the Linux kernel can produce a hung task warning message in its log. Searching the Internet and the kernel documentation, you can find a brief explanation that the kernel process is stuck in the uninterruptable state and hasn’t been scheduled on the CPU for an unexpectedly long period of time. That explains the warning’s meaning, but doesn’t provide the reason it occurred. In this blog post we’re going to explore how the hung task warning works, why it happens, whether it is a bug in the Linux kernel or application itself, and whether it is worth monitoring at all.

INFO: task XXX:1495882 blocked for more than YYY seconds.

The hung task message in the kernel log looks like this:

INFO: task XXX:1495882 blocked for more than YYY seconds.
     Tainted: G          O       6.6.39-cloudflare-2024.7.3 #1
"echo 0 > /proc/sys/kernel/hung_task_timeout_secs" disables this message.
task:XXX         state:D stack:0     pid:1495882 ppid:1      flags:0x00004002
. . .

Processes in Linux can be in different states. Some of them are running or ready to run on the CPU — they are in the TASK_RUNNING state. Others are waiting for some signal or event to happen, e.g. network packets to arrive or terminal input from a user. They are in a TASK_INTERRUPTIBLE state and can spend an arbitrary length of time in this state until being woken up by a signal. The most important thing about these states is that they still can receive signals, and be terminated by a signal. In contrast, a process in the TASK_UNINTERRUPTIBLE state is waiting only for certain special classes of events to wake them up, and can’t be interrupted by a signal. The signals are not delivered until the process emerges from this state and only a system reboot can clear the process. It’s marked with the letter D in the log shown above.

What if this wake up event doesn’t happen or happens with a significant delay? (A “significant delay” may be on the order of seconds or minutes, depending on the system.) Then our dependent process is hung in this state. What if this dependent process holds some lock and prevents other processes from acquiring it? Or if we see many processes in the D state? Then it might tell us that some of the system resources are overwhelmed or are not working correctly. At the same time, this state is very valuable, especially if we want to preserve the process memory. It might be useful if part of the data is written to disk and another part is still in the process memory — we don’t want inconsistent data on a disk. Or maybe we want a snapshot of the process memory when the bug is hit. To preserve this behaviour, but make it more controlled, a new state was introduced in the kernel: TASK_KILLABLE — it still protects a process, but allows termination with a fatal signal. 

How Linux identifies the hung process

The Linux kernel has a special thread called khungtaskd. It runs regularly depending on the settings, iterating over all processes in the D state. If a process is in this state for more than YYY seconds, we’ll see a message in the kernel log. There are settings for this daemon that can be changed according to your wishes:

$ sudo sysctl -a --pattern hung
kernel.hung_task_all_cpu_backtrace = 0
kernel.hung_task_check_count = 4194304
kernel.hung_task_check_interval_secs = 0
kernel.hung_task_panic = 0
kernel.hung_task_timeout_secs = 10
kernel.hung_task_warnings = 200

At Cloudflare, we changed the notification threshold kernel.hung_task_timeout_secs from the default 120 seconds to 10 seconds. You can adjust the value for your system depending on configuration and how critical this delay is for you. If the process spends more than hung_task_timeout_secs seconds in the D state, a log entry is written, and our internal monitoring system emits an alert based on this log. Another important setting here is kernel.hung_task_warnings — the total number of messages that will be sent to the log. We limit it to 200 messages and reset it every 15 minutes. It allows us not to be overwhelmed by the same issue, and at the same time doesn’t stop our monitoring for too long. You can make it unlimited by setting the value to “-1”.

To better understand the root causes of the hung tasks and how a system can be affected, we’re going to review more detailed examples. 

Example #1 or XFS

Typically, there is a meaningful process or application name in the log, but sometimes you might see something like this:

INFO: task kworker/13:0:834409 blocked for more than 11 seconds.
 	Tainted: G      	O   	6.6.39-cloudflare-2024.7.3 #1
"echo 0 > /proc/sys/kernel/hung_task_timeout_secs" disables this message.
task:kworker/13:0	state:D stack:0 	pid:834409 ppid:2   flags:0x00004000
Workqueue: xfs-sync/dm-6 xfs_log_worker

In this log, kworker is the kernel thread. It’s used as a deferring mechanism, meaning a piece of work will be scheduled to be executed in the future. Under kworker, the work is aggregated from different tasks, which makes it difficult to tell which application is experiencing a delay. Luckily, the kworker is accompanied by the Workqueue line. Workqueue is a linked list, usually predefined in the kernel, where these pieces of work are added and performed by the kworker in the order they were added to the queue. The Workqueue name xfs-sync and the function which it points to, xfs_log_worker, might give a good clue where to look. Here we can make an assumption that the XFS is under pressure and check the relevant metrics. It helped us to discover that due to some configuration changes, we forgot no_read_workqueue / no_write_workqueue flags that were introduced some time ago to speed up Linux disk encryption.

Summary: In this case, nothing critical happened to the system, but the hung tasks warnings gave us an alert that our file system had slowed down.

Example #2 or Coredump

Let’s take a look at the next hung task log and its decoded stack trace:

INFO: task test:964 blocked for more than 5 seconds.
      Not tainted 6.6.72-cloudflare-2025.1.7 #1
"echo 0 > /proc/sys/kernel/hung_task_timeout_secs" disables this message.
task:test            state:D stack:0     pid:964   ppid:916    flags:0x00004000
Call Trace:
<TASK>
__schedule (linux/kernel/sched/core.c:5378 linux/kernel/sched/core.c:6697) 
schedule (linux/arch/x86/include/asm/preempt.h:85 (discriminator 13) linux/kernel/sched/core.c:6772 (discriminator 13)) 
[do_exit (linux/kernel/exit.c:433 (discriminator 4) linux/kernel/exit.c:825 (discriminator 4)) 
? finish_task_switch.isra.0 (linux/arch/x86/include/asm/irqflags.h:42 linux/arch/x86/include/asm/irqflags.h:77 linux/kernel/sched/sched.h:1385 linux/kernel/sched/core.c:5132 linux/kernel/sched/core.c:5250) 
do_group_exit (linux/kernel/exit.c:1005) 
get_signal (linux/kernel/signal.c:2869) 
? srso_return_thunk (linux/arch/x86/lib/retpoline.S:217) 
? hrtimer_try_to_cancel.part.0 (linux/kernel/time/hrtimer.c:1347) 
arch_do_signal_or_restart (linux/arch/x86/kernel/signal.c:310) 
? srso_return_thunk (linux/arch/x86/lib/retpoline.S:217) 
? hrtimer_nanosleep (linux/kernel/time/hrtimer.c:2105) 
exit_to_user_mode_prepare (linux/kernel/entry/common.c:176 linux/kernel/entry/common.c:210) 
syscall_exit_to_user_mode (linux/arch/x86/include/asm/entry-common.h:91 linux/kernel/entry/common.c:141 linux/kernel/entry/common.c:304) 
? srso_return_thunk (linux/arch/x86/lib/retpoline.S:217) 
do_syscall_64 (linux/arch/x86/entry/common.c:88) 
entry_SYSCALL_64_after_hwframe (linux/arch/x86/entry/entry_64.S:121) 
</TASK>

The stack trace says that the process or application test was blocked for more than 5 seconds. We might recognise this user space application by the name, but why is it blocked? It’s always helpful to check the stack trace when looking for a cause. The most interesting line here is do_exit (linux/kernel/exit.c:433 (discriminator 4) linux/kernel/exit.c:825 (discriminator 4)). The source code points to the coredump_task_exit function. Additionally, checking the process metrics revealed that the application crashed during the time when the warning message appeared in the log. When a process is terminated based on some set of signals (abnormally), the Linux kernel can provide a core dump file, if enabled. The mechanism — when a process terminates, the kernel makes a snapshot of the process memory before exiting and either writes it to a file or sends it through the socket to another handler — can be systemd-coredump or your custom one. When it happens, the kernel moves the process to the D state to preserve its memory and early termination. The higher the process memory usage, the longer it takes to get a core dump file, and the higher the chance of getting a hung task warning.

Let’s check our hypothesis by triggering it with a small Go program. We’ll use the default Linux coredump handler and will decrease the hung task threshold to 1 second.

Coredump settings:

$ sudo sysctl -a --pattern kernel.core
kernel.core_pattern = core
kernel.core_pipe_limit = 16
kernel.core_uses_pid = 1

You can make changes with sysctl:

$ sudo sysctl -w kernel.core_uses_pid=1

Hung task settings:

$ sudo sysctl -a --pattern hung
kernel.hung_task_all_cpu_backtrace = 0
kernel.hung_task_check_count = 4194304
kernel.hung_task_check_interval_secs = 0
kernel.hung_task_panic = 0
kernel.hung_task_timeout_secs = 1
kernel.hung_task_warnings = -1

Go program:

$ cat main.go
package main

import (
	"os"
	"time"
)

func main() {
	_, err := os.ReadFile("test.file")
	if err != nil {
		panic(err)
	}
	time.Sleep(8 * time.Minute) 
}

This program reads a 10 GB file into process memory. Let’s create the file:

$ yes this is 10GB file | head -c 10GB > test.file

The last step is to build the Go program, crash it, and watch our kernel log:

$ go mod init test
$ go build .
$ GOTRACEBACK=crash ./test
$ (Ctrl+\)

Hooray! We can see our hung task warning:
$ sudo dmesg -T | tail -n 31
INFO: task test:8734 blocked for more than 22 seconds.
      Not tainted 6.6.72-cloudflare-2025.1.7 #1
      Blocked by coredump.
"echo 0 > /proc/sys/kernel/hung_task_timeout_secs" disables this message.
task:test            state:D stack:0     pid:8734  ppid:8406   task_flags:0x400448 flags:0x00004000

By the way, have you noticed the Blocked by coredump. line in the log? It was recently added to the upstream code to improve visibility and remove the blame from the process itself. The patch also added the task_flags information, as Blocked by coredump is detected via the flag PF_POSTCOREDUMP, and knowing all the task flags is useful for further root-cause analysis.

Summary: This example showed that even if everything suggests that the application is the problem, the real root cause can be something else — in this case, coredump.

Example #3 or rtnl_mutex

This one was tricky to debug. Usually, the alerts are limited by one or two different processes, meaning only a certain application or subsystem experiences an issue. In this case, we saw dozens of unrelated tasks hanging for minutes with no improvements over time. Nothing else was in the log, most of the system metrics were fine, and existing traffic was being served, but it was not possible to ssh to the server. New Kubernetes container creations were also stalling. Analyzing the stack traces of different tasks initially revealed that all the traces were limited to just three functions:

rtnetlink_rcv_msg+0x9/0x3c0
dev_ethtool+0xc6/0x2db0 
bonding_show_bonds+0x20/0xb0

Further investigation showed that all of these functions were waiting for rtnl_lock to be acquired. It looked like some application acquired the rtnl_mutex and didn’t release it. All other processes were in the D state waiting for this lock.

The RTNL lock is primarily used by the kernel networking subsystem for any network-related config, for both writing and reading. The RTNL is a global mutex lock, although upstream efforts are being made for splitting up RTNL per network namespace (netns).

From the hung task reports, we can observe the “victims” that are being stalled waiting for the lock, but how do we identify the task that is holding this lock for too long? For troubleshooting this, we leveraged BPF via a bpftrace script, as this allows us to inspect the running kernel state. The kernel’s mutex implementation has a struct member called owner. It contains a pointer to the task_struct from the mutex-owning process, except it is encoded as type atomic_long_t. This is because the mutex implementation stores some state information in the lower 3-bits (mask 0x7) of this pointer. Thus, to read and dereference this task_struct pointer, we must first mask off the lower bits (0x7).

Our bpftrace script to determine who holds the mutex is as follows:

#!/usr/bin/env bpftrace
interval:s:10 {
  $rtnl_mutex = (struct mutex *) kaddr("rtnl_mutex");
  $owner = (struct task_struct *) ($rtnl_mutex->owner.counter & ~0x07);
  if ($owner != 0) {
    printf("rtnl_mutex->owner = %u %s\n", $owner->pid, $owner->comm);
  }
}

In this script, the rtnl_mutex lock is a global lock whose address can be exposed via /proc/kallsyms – using bpftrace helper function kaddr(), we can access the struct mutex pointer from the kallsyms. Thus, we can periodically (via interval:s:10) check if someone is holding this lock.

In the output we had this:

rtnl_mutex->owner = 3895365 calico-node

This allowed us to quickly identify calico-node as the process holding the RTNL lock for too long. To quickly observe where this process itself is stalled, the call stack is available via /proc/3895365/stack. This showed us that the root cause was a Wireguard config change, with function wg_set_device() holding the RTNL lock, and peer_remove_after_dead() waiting too long for a napi_disable() call. We continued debugging via a tool called drgn, which is a programmable debugger that can debug a running kernel via a Python-like interactive shell. We still haven’t discovered the root cause for the Wireguard issue and have asked the upstream for help, but that is another story.

Summary: The hung task messages were the only ones which we had in the kernel log. Each stack trace of these messages was unique, but by carefully analyzing them, we could spot similarities and continue debugging with other instruments.

Epilogue

Your system might have different hung task warnings, and we have many others not mentioned here. Each case is unique, and there is no standard approach to debug them. But hopefully this blog post helps you better understand why it’s good to have these warnings enabled, how they work, and what the meaning is behind them. We tried to provide some navigation guidance for the debugging process as well:

  • analyzing the stack trace might be a good starting point for debugging it, even if all the messages look unrelated, like we saw in example #3

  • keep in mind that the alert might be misleading, pointing to the victim and not the offender, as we saw in example #2 and example #3

  • if the kernel doesn’t schedule your application on the CPU, puts it in the D state, and emits the warning – the real problem might exist in the application code

Good luck with your debugging, and hopefully this material will help you on this journey!
Monitoring Sensor Data with Zabbix and Modbus Protocol

Post Syndicated from Nyein Chan Zaw original https://blog.zabbix.com/monitoring-sensor-data-with-zabbix-and-modbus-protocol/29471/

This week’s blog entry comes to us from Nyein Chan Zaw, who is based in Bangkok, Thailand and works as an Infrastructure Specialist for Green Will Solution. Read on to see how he uses his integrating a Modbus protocol with Zabbix to monitor data from temperature, humidity, and smoke sensors — and display their metrics on a Zabbix dashboard.

Step 1: Collecting Sensor Data via Modbus Protocol

This snapshot shows how all three sensors are synchronized with the Modbus protocol, confirming that the communication is operational.

In the initial setup, the temperature, humidity, and smoke sensors transmit their data to the Modbus protocol. This data synchronization can be visualized using Modbus polling software, where the values from each sensor are displayed in real-time.

Step 2: Configuring Modbus Files on Zabbix Agent

This snapshot demonstrates the configuration of three MB files corresponding to the three sensors.

To enable Zabbix to communicate with Modbus, the Modbus configuration (MB) files must be set up in the Zabbix Agent configuration file on the Zabbix server. Each sensor requires an individual MB configuration entry, specifying the Modbus parameters such as function code, register address, and data type.

Step 3: Creating a Host for Modbus Protocol in Zabbix

Next, a Zabbix host must be created to represent the Modbus protocol device.

This snapshot highlights the host creation process with the associated IP address and configuration details.

During this process, assign the Modbus protocol’s IP address as the host’s interface. Configure the interface to communicate with the Zabbix server using the Zabbix agent.

Step 4: Configuring Items for Each Sensor

Each sensor requires an item in Zabbix to capture its data.

This snapshot shows how items are configured for each sensor.

For every item, specify the Name for identification (e.g., Temperature Sensor). Define the Key, which includes the Modbus protocol function and register settings, to ensure accurate data retrieval.

Step 5: Viewing and Utilizing Sensor Data in Zabbix

This snapshot displays the Zabbix dashboard, showcasing data from all three sensors.

Once the host and items are configured, Zabbix starts collecting data from the Modbus protocol. This data is displayed in the Zabbix interface, where metrics for temperature, humidity, and smoke are updated in real-time. Additionally, a custom dashboard can be created to visualize all three sensors’ data at a glance, providing actionable insights for monitoring and decision-making.

Conclusion

Integrating Modbus with Zabbix streamlines the monitoring of sensor data, making it easy to collect, visualize, and act upon critical metrics. This process demonstrates Zabbix’s flexibility and scalability in managing industrial protocols and data sources, ensuring robust monitoring for diverse applications.

If you’re looking to implement similar solutions or need help integrating Modbus with Zabbix, feel free to reach out in the comments below!

The post Monitoring Sensor Data with Zabbix and Modbus Protocol appeared first on Zabbix Blog.

Change is the Only Constant: 2024 in Review

Post Syndicated from Michael Kammer original https://blog.zabbix.com/change-is-the-only-constant-2024-in-review/29528/

Time waits for no one, and as impossible as it may seem, one of the most consequential years in the history of Zabbix is already in the books. You can be forgiven for feeling at times like we were trying to cram a decade of events into a single year, which is why we’ve prepared this handy look back at the highlights of 2024 – just in case there’s anything you were too busy to notice as it happened!

Re-imagining the product

One of the year’s unquestioned highlights was the long-awaited release of Zabbix Cloud on October 1. As our first new product release since the creation of Zabbix, Zabbix Cloud is designed to provide the Zabbix features our community members know and love, but with easier deployment and management as well as automatic upgrades and easier scalability.

To celebrate the release itself, we held a release party at our Riga HQ with members of our global community who were in town for Zabbix Summit 2024, which kicked off a few days later. The release definitely got our community talking – the level of interest in this new “portable” version of Zabbix exceeded even our highest expectations.

Our team also released Zabbix 7.0 LTS on June 4, packed full of improvements and upgrades that our users have been asking for, including upgraded performance and scalability, new ways to visualize data, faster network discovery speed, and more. We followed that in December with the release of Zabbix 7.2, which added improved monitoring features and workflows as well as a host of new templates.

It can’t be stressed enough – all these new products, innovations, and updates were the result of feedback and suggestions from our global community. We listen, we learn, and we take your ideas to heart!

Security first

In 2024, Zabbix transitioned to the ISO/IEC 27001:2022 certification, with an extended scope to cover Zabbix Cloud. This milestone also includes compliance with ISO/IEC 27017:2015, further enhancing cloud-specific security controls.

Meanwhile, the HackerOne bug bounty program continues to be a success. 2024 brought us 33 valid submissions, and we paid $35,000 in bounties. Out of those, we have already fixed and published 24 vulnerabilities for source code.

The Zabbix CVE (Common Vulnerabilities and Exposures) program and processes are also continuing to mature. Recently, an audit was performed against our organization’s CVE submission for 40 submissions in the NIST NVD (National Vulnerability Database). Not only did we pass the audit and gain contributor status, but Zabbix is currently the only CVE Numbering Authorities (CNA) in Latvia.

Making our presence felt

Our community members piled up the frequent flier miles as we traveled the globe to keep in touch with our ever-expanding community and win over new converts. The events we took part in this year included the following:

• 31 meetings (with first-time visits to many destinations in North America)
• 1 forum in Mexico City
• 18 meetups (both online and in a variety of global locations)
• 4 conferences (Benelux, China, Japan, and Latin America)
• Far too many exhibitions, trade fairs, and expos to list conveniently
• One extremely successful Zabbix Summit in Riga

“The long hours and even longer flights really paid off, as this year was our most successful yet in terms of new business. The events we held in North America were especially helpful in terms of breaking new ground. We understood that we have an amazing Zabbix community in the United States and a much bigger market to work with.” – Ronalds Sulcs, Zabbix Head of Sales

A year of continuous growth

2024 saw us add new team members in every location we operate in, while also recruiting remote workers from nearly every corner of the globe. All told, the team grew by 30 people, which means we are now almost 200 strong! Meanwhile, the Partners team was also operating at full throttle, adding 12 new highly-skilled Certified Partners and 16 Resellers in locations from Australia to Morocco. All partners and resellers were chosen for their unique blend of experience and expertise, and we’re confident that they’ll provide best-in-class knowledge where it’s needed most.

The fact that we’ve managed to build on our status as an employer of choice across three continents while adding an ever-increasing number of quality partners in every corner of the globe speaks to the hard work and competence of our colleagues as well as the quality of the products and services we provide. Congratulations to everyone who did their part to make sure we continue to add talent and expertise!

Giving back

2024 was an exceptionally successful year in terms of bringing our products and services to the world, but we’re proud of the fact that we also managed to export our values of openness, transparency, and a desire to give back to the communities we live and work in. This took multiple forms throughout the year:

• The LatAm team worked with the DEDICA Foundation – Foundation for Digital Development and Open Knowledge to create the Zabbix Innova Challenge. The challenge is designed to encourage creativity and stimulate technological development in local communities through a Hackathon and other activities, with the goal of introducing Zabbix to a new generation of tech talent.
• In December, we made a generous donation to Pārtikas banka “Paēdušai Latvijai” (Food Bank “For a Full Latvia”) in support of their mission of getting nutritious food to communities in need. We also gave to support Bērnu slimnīcas fonds, Latvijas Bērnu fonds, Autisma atbalsta punkts, and Ziedot.lv – all with the goal of supporting children’s health, while our employees in the Riga office prepared gifts for senior citizens at the Rīga Social Care Center Mežciems as part of the “Eņģeļa pasts (Angel’s Mail)” charity project, Santa’s Workshop.
• The end of the year also saw us contribute €50,000 to Dod pieci!, the Latvian charity marathon organized by Latvijas Radio, Latvijas Televīzija, LSM.lv, and Ziedot.lv. The marathon helps make life-saving cancer treatment more affordable.

It’s been our experience that making a difference and donating to good causes reinforces a shared commitment to the company as well as to each other. We’d like to thank and congratulate everyone who took part in our outreach efforts over the past year!

Getting noticed

The news about what we got up to in 2024 seemed to be everywhere, as tech journals, newspapers, and global organizations showered us with positive publicity. At Interop Tokyo 2024, the Zabbix Japan team picked up the prestigious “Best of Show” Grand Prize in the Management and Monitoring category for the Zabbix 7.0 LTS release. The award is granted by a jury made up of some of the world’s most knowledgeable IT and monitoring experts, so recognition was truly an honor.

In Latin America, Milenio published a profile of our CEO and Founder Alexei Vladishev that brought the Zabbix story to thousands of new readers, while Mexico’s Encuentro Vidal marked the occasion of Zabbix Conference Mexico in November with a look at how Zabbix is helping countries in the region on their journey to digital transformation.

Globo published a well-written and informative piece that explored how the Brazilian city of Extrema has been investing in new technologies (with Zabbix prominent among them) in order to better serve the population of the city and make its administration more efficient and transparent.

Carrying our momentum into 2025

As 2025 gets underway, remember to stay on top of Zabbix news by following us on social media, reading our blog, and checking our forum.

“2024 was an eventful year that was full of excitement, growth, and change. It was the year we made Zabbix Cloud a reality, and a true milestone in the growth of our company and our community. I’m sure that everyone in the Zabbix family is excited to see what our 20th Anniversary year of 2025 will bring!” – Alexei Vladishev, Zabbix Founder and CEO


The post Change is the Only Constant: 2024 in Review appeared first on Zabbix Blog.

Solving Log Monitoring Challenges at SEB Bank

Post Syndicated from Giedrius Stasiulionis original https://blog.zabbix.com/solving-log-monitoring-challenges-at-seb-bank/29153/

SEB Bank is a major financial services group based in Stockholm, Sweden. It serves northern Europe, particularly the Nordic and Baltic regions. Known for its digital innovation and commitment to sustainability, SEB offers banking, investment, and financial advisory services to individuals, businesses, and institutions, focusing on long-term relationships and financial stability. This case study, which shows how Zabbix helped SEB solve its log monitoring challenges, discusses aspects specific to SEB’s operations in the Baltics, where distinct systems and structures are in place but are aligned with the group’s overall approach.

The challenge

Between 2016 and 2020, SEB launched a unified IT platform for all three Baltic countries. They encountered a wide variety of challenges, including a distinct need to unify the monitoring area. Different countries had different tools and different attitudes regarding the way monitoring should operate. After numerous discussions and weighing the pros and cons of different monitoring tools, SEB concluded that the most effective way to achieve unification would be to (re)implement everything necessary with Zabbix.

It turned out that a great deal of valuable data for monitoring resides in logs. The logs varied in update frequency and structure, as did the requirements for data extraction. Some monitoring items were simple regex patterns to count matching entities or catch errors, while others had more complex logic, such as joining multiple lines for evaluation or dynamically detecting specific patterns to observe.

At the start of SEB’s journey with Zabbix, they were using version 3.0, which came with some now long-forgotten limitations:

  • No log.count[*] item yet
  • No PCRE regular expressions – only ERE was available
  • Very limited dashboard and visualization capabilities

The solution

To address all the log-related challenges, SEB chose to leverage Zabbix’s “UserParameter” capabilities. This feature is invaluable for extending Zabbix functionality.

log.discovery

This custom approach relies on the ability to effectively convert regex capturing groups into LLD (Low-Level Discovery) objects. When new elements that need monitoring appear in the logs, corresponding monitoring objects can be automatically created in Zabbix. This process was covered in more detail at Zabbix Summit 2023.

For instance, an effective set of metrics is extracted from logs to monitor the SEB mobile app. Request processing durations are logged alongside other parameters, enabling efficient grouping, such as by endpoint name and HTTP status code. This approach accommodates a wide range of potential combinations for “endpoint + HTTP status code”:

[root@linux ~]# ./log_discovery.sh "${my_log}" 1000000 COMPONENT "response\":.\"status\":(\d{3}).*uriPattern\":\"([^ ]+)\",.timing" | jq '.' | grep -c COMPONENT_1
205
[root@linux ~]#

LLD is able to gather them all:

For each discovered couple, monitoring of request processing durations is added, both for individual durations and 1 minute averages:

Certain significant combinations are enhanced with triggers, efficiently managed using the “Override” section in the LLD configuration to ensure they are created only for specific cases. So with this approach, some unexpected slowness can be nicely caught:

log.reader

For complex data collection scenarios, there was a need to implement a solution that allows data to be extracted from logs with minimal limitations. The approach was to create a log reading mechanism that could support any required data extraction logic on top of it. This was covered in more detail at Zabbix Summit 2024.

Zabbix agent 2

In addition to the mentioned custom log processing techniques, SEB had a good reason to use “Zabbix agent 2”. Both log[*] and log.count[*] are of the “Active” item type. These items are not processed in parallel by the Zabbix agent. In places with a large number of log-based items, “Zabbix Agent 2” was used, because it supports the concurrent processing of active checks.

The results

The ability to use LLD on logs was a game-changer and a lifesaver for SEB. Imagine hundreds of different items discovered from a single rule, along with the requirement to monitor any new entity matching a specific pattern as soon as it appears. Without LLD, meeting such a requirement would have been simply impossible. This approach covers many different areas, including mission-critical metrics such as counts of various requests and processing durations.

The ability to slice logs themselves and create any needed logic on top makes almost any custom log monitoring requirement possible. It gives the ability to analyze data in ways that wouldn’t be possible otherwise (e.g. average duration monitoring for large set of data).

In conclusion

SEB Bank in the Baltics relies heavily on data collection from logs. Zabbix is flexible enough to meet most of their needs when it comes to log monitoring, and – most importantly – it allows for custom implementations where required. This flexibility is highly appreciated, as it removes many barriers when monitoring the various components of SEB’s IT ecosystem and business functions.

The post Solving Log Monitoring Challenges at SEB Bank appeared first on Zabbix Blog.