Tag Archives: news

DNS over HTTPS is now available in Amazon Route 53 Resolver

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/dns-over-https-is-now-available-in-amazon-route-53-resolver/

Starting today, Amazon Route 53 Resolver supports using the DNS over HTTPS (DoH) protocol for both inbound and outbound Resolver endpoints. As the name suggests, DoH supports HTTP or HTTP/2 over TLS to encrypt the data exchanged for Domain Name System (DNS) resolutions.

Using TLS encryption, DoH increases privacy and security by preventing eavesdropping and manipulation of DNS data as it is exchanged between a DoH client and the DoH-based DNS resolver.

This helps you implement a zero-trust architecture where no actor, system, network, or service operating outside or within your security perimeter is trusted and all network traffic is encrypted. Using DoH also helps follow recommendations such as those described in this memorandum of the US Office of Management and Budget (OMB).

DNS over HTTPS support in Amazon Route 53 Resolver
You can use Amazon Route 53 Resolver to resolve DNS queries in hybrid cloud environments. For example, it allows AWS services access for DNS requests from anywhere within your hybrid network. To do so, you can set up inbound and outbound Resolver endpoints:

  • Inbound Resolver endpoints allow DNS queries to your VPC from your on-premises network or another VPC.Amazon Route 53 Resolver inbound endpoint architecture.
  • Outbound Resolver endpoints allow DNS queries from your VPC to your on-premises network or another VPC.Amazon Route 53 Resolver outbound endpoint architecture.

After you configure the Resolver endpoints, you can set up rules that specify the name of the domains for which you want to forward DNS queries from your VPC to an on-premises DNS resolver (outbound) and from on-premises to your VPC (inbound).

Now, when you create or update an inbound or outbound Resolver endpoint, you can specify which protocols to use:

  • DNS over port 53 (Do53), which is using either UDP or TCP to send the packets.
  • DNS over HTTPS (DoH), which is using TLS to encrypt the data.
  • Both, depending on which one is used by the DNS client.
  • For FIPS compliance, there is a specific implementation (DoH-FIPS) for inbound endpoints.

Let’s see how this works in practice.

Using DNS over HTTPS with Amazon Route 53 Resolver
In the Route 53 console, I choose Inbound endpoints from the Resolver section of the navigation pane. There, I choose Create inbound endpoint.

I enter a name for the endpoint, select the VPC, the security group, and the endpoint type (IPv4, IPv6, or dual-stack). To allow using both encrypted and unencrypted DNS resolutions, I select Do53, DoH, and DoH-FIPS in the Protocols for this endpoint option.

Console screenshot.

After that, I configure the IP addresses for DNS queries. I select two Availability Zones and, for each, a subnet. For this setup, I use the option to have the IP addresses automatically selected from those available in the subnet.

After I complete the creation of the inbound endpoint, I configure the DNS server in my network to forward requests for the amazonaws.com domain (used by AWS service endpoints) to the inbound endpoint IP addresses.

Similarly, I create an outbound Resolver endpoint and and select both Do53 and DoH as protocols. Then, I create forwarding rules that tell for which domains the outbound Resolver endpoint should forward requests to the DNS servers in my network.

Now, when the DNS clients in my hybrid environment use DNS over HTTPS in their requests, DNS resolutions are encrypted. Optionally, I can enforce encryption and select only DoH in the configuration of inbound and outbound endpoints.

Things to know
DNS over HTTPS support for Amazon Route 53 Resolver is available today in all AWS Regions where Route 53 Resolver is offered, including GovCloud Regions and Regions based in China.

DNS over port 53 continues to be the default for inbound or outbound Resolver endpoints. In this way, you don’t need to update your existing automation tooling unless you want to adopt DNS over HTTPS.

There is no additional cost for using DNS over HTTPS with Resolver endpoints. For more information, see Route 53 pricing.

Start using DNS over HTTPS with Amazon Route 53 Resolver to increase privacy and security for your hybrid cloud environments.

— Danilo

The AWS Canada West (Calgary) Region is now available

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/the-aws-canada-west-calgary-region-is-now-available/

Today, we are opening a new Region in Canada. AWS Canada West (Calgary), also known as ca-west-1, is the thirty-third AWS Region. It consists of three Availability Zones, for a new total of 105 Availability Zones globally.

This second Canadian Region allows you to architect multi-Region infrastructures that meet five nines of availability while keeping your data in the country.

A global footprint
Our approach to building infrastructure is fundamentally different from other providers. At the core of our global infrastructure is a Region. An AWS Region is a physical location in the world where we have multiple Availability Zones. Availability Zones consist of one or more discrete data centers, each with redundant power, networking, and connectivity, housed in separate facilities. Unlike with other cloud providers, who often define a region as a single data center, having multiple Availability Zones allows you to operate production applications and databases that are more highly available, fault tolerant, and scalable than would be possible from a single data center.

AWS has more than 17 years of experience building its global infrastructure. And there’s no compression algorithm for experience, especially when it comes to scale, security, and performance.

Canadian customers of every size, including global brands like BlackBerry, CI Financial, Keyera, KOHO, Maple Leaf Sports & Entertainment (MLSE), Nutrien, Sun Life, TELUS, and startups like Good Chemistry and Cohere, and public sector organizations like the University of Calgary and Natural Resources Canada (NRCan), are already running workloads on AWS. They choose AWS for its security, performance, flexibility, and global presence.

AWS Global Infrastructure, including AWS Local Zones and AWS Outposts, gives our customers the flexibility to deploy workloads close to their customers to minimize network latency. For example, one customer that has benefited from AWS flexibility is Canadian decarbonization technology scale-up, BrainBox AI. BrainBox AI uses cloud-based artificial intelligence (AI) and machine learning (ML) on AWS to help building owners around the world reduce HVAC emissions by up to 40 percent and energy consumption by up to 25 percent. The AWS Global Infrastructure allows their solution to manage with low latency hundreds of buildings in over 20 countries, 24-7.

Services available
You can deploy your workloads on any of the C5, M5, M5d, R5, C6g, C6gn, C6i, C6id, M6g, M6gd, M6i, M6id, R6d, R6i, R6id, I4i, I3en, T3, and T4g instance families. The new AWS Canada West (Calgary) has 65 AWS services available at launch. Here is the list, sorted by alphabetical order: Amazon API Gateway, AWS AppConfig, AWS Application Auto Scaling, Amazon Aurora, Aurora PostgreSQL, AWS Batch, AWS Certificate Manager, AWS CloudFormation, Amazon CloudFront, AWS Cloud Map, AWS CloudTrail, Amazon CloudWatch, Amazon CloudWatch Events, Amazon CloudWatch Logs, AWS CodeDeploy, AWS Config, AWS Database Migration Service (AWS DMS), AWS DataSync, AWS Direct Connect, Amazon DynamoDB, Amazon ElastiCache, Amazon Elastic Block Store (Amazon EBS), Amazon Elastic Compute Cloud (Amazon EC2), Amazon EC2 Auto Scaling, Amazon Elastic Container Registry (Amazon ECR), Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), Elastic Load Balancing, Elastic Load Balancing – Gateway (GWLB), Elastic Load Balancing – Network (NLB), Amazon EMR, Amazon EventBridge, AWS Fargate, AWS Health Dashboard, AWS Identity and Access Management (IAM), Amazon Kinesis Data Firehose, Amazon Kinesis Data Streams, AWS Key Management Service (AWS KMS), AWS Lambda, AWS Management Console, AWS Marketplace, Amazon OpenSearch Service, AWS Organizations, Amazon Redshift, Amazon Relational Database Service (Amazon RDS), AWS Resource Access Manager, Resource Groups, Amazon Route 53, AWS Secrets Manager, AWS Security Hub, AWS Security Token Service, Service Quotas, AWS Shield Standard, Amazon Simple Notification Service (Amazon SNS), Amazon Simple Queue Service (Amazon SQS), Amazon Simple Storage Service (Amazon S3), Amazon Simple Workflow Service (Amazon SWF), AWS Site-to-Site VPN, AWS Step Functions, AWS Support API, AWS Systems Manager, AWS Trusted Advisor, Amazon Virtual Private Cloud (Amazon VPC), VM Import/Export, and AWS X-Ray.

AWS in Canada
We have been supporting our customers and partners with infrastructure in Canada since December 2016, when the first Canadian AWS Region, AWS Canada (Central), was launched. In the same year, we launched Amazon CloudFront locations in Toronto and Montreal to better serve your customers in the region. To date, there are ten CloudFront points of presence (PoPs) in Canada: five in Toronto, four in Montreal, and one in Vancouver. We also have engineering teams located in multiple cities in the country.

From 2016–2021, AWS has invested over 2.57 billion CAD (1.9 billion USD) in Canada and plans to invest up to 24.8 billion CAD (18.3 billion USD) by 2037 in the two Regions. Using the input-output methodology and statistical tables provided by Statistics Canada, we estimate that the planned investment will add 43.02 billion CAD (31 billion USD) to the gross domestic product (GDP) of Canada and support more than 9,300 full-time equivalent (FTE) jobs in the Canadian economy.

In addition to providing our customers with world-class infrastructure benefits, Amazon is committed to reaching net zero carbon across its business by 2040 and is on a path to powering its operations with 100 percent renewable energy by 2025. In 2022, 90 percent of the electricity consumed by Amazon was attributable to renewable energy sources. Additionally, AWS has a goal to be water positive by 2030, returning more water to communities than it uses in its direct operations. Amazon has a total of four renewable energy projects in Canada: three south of Calgary and one close to Edmonton. According to BloombergNEF, Amazon is the largest corporate purchaser of renewable energy in the country (and the world). These projects generate more than 2.3 million megawatt hours (MWH) of clean energy–enough to power 1.69 million Canadian homes.

Education is one of our top priorities as well. Since 2017, we have trained more than 200,000 Canadians on cloud computing skills through free and paid AWS Training and Certification programs. Learners of various skill levels, roles, and backgrounds can build knowledge and practical skills with more than 600 free online courses in up to 14 languages on AWS Skills Builder. Amazon is committed to providing 29 million people around the world with free cloud computing skills training by 2025.

Security
Customers around the world trust AWS to keep their data safe, and keeping their workloads secure and confidential is foundational to how we operate. Since the inception of AWS, we have relentlessly innovated on security, privacy tools, and practices to meet, and even exceed, our customers’ expectations.

For example, you decide where to store your data and who can access it. Services such as AWS CloudTrail allow you to verify how and when data are accessed. Our virtualization technology, AWS Nitro System, has been designed to restrict any operator access to customer data. This means no person, or even service, from AWS can access data when it is being used in an EC2 instance. NCC Group, a leading cybersecurity consulting firm based in the United Kingdom, audited the Nitro architecture and affirmed our claims.

Our core infrastructure is built to satisfy the security requirements of the military, global banks, and other high-sensitivity organizations.

In Canada, Neo Financial is a financial tech startup that uses the elasticity of the AWS Cloud to scale its business. They chose AWS in 2019 because we helped them to meet their regulatory requirements. They use EC2 for their core infrastructure, S3 for highly durable storage, Amazon GuardDuty to improve their security posture, and CloudFront to improve performance for their customers.

Performance
The AWS Global Infrastructure is built for performance, offering the lowest latency, lowest packet loss, and highest overall network quality. This is achieved with a fully redundant 400 GbE fiber network backbone, often providing many terabits of capacity between Regions.

To help provide Canadian customers with even lower latency, we have announced two AWS Local Zones in Toronto and Vancouver.

Performance is specially important when you are streaming your favorite TV show. Calgary-based Kidoodle.TV offers a streaming service for children. They have more than 100 million app downloads worldwide and more than 1 billion ad seconds for sale every 2 days. Using AWS, Kidoodle.TV was able to build the same service architecture that multibillion-dollar companies can deploy, which allowed them to seamlessly scale up from 400,000 monthly active users to 12 million in a year.

Additional things to know
We preannounced 12 additional Availability Zones in four future Regions in Malaysia, New Zealand, Thailand, and the AWS European Sovereign Cloud. We will be happy to share more information on these Regions so, stay tuned.

I can’t wait to discover how you will innovate and what amazing services you will deploy on this new AWS Region. Go build and deploy your infrastructure on ca-west-1 today.

— seb


Aujourd’hui, nous inaugurons une nouvelle Région Amazon Web Services (AWS) au Canada. La Région AWS Canada Ouest (Calgary), également connue sous le nom ca‑west‑1, est la 33e Région AWS. Elle compte trois Zones de disponibilité, emmenant ainsi le total des Zones de disponibilité à travers le monde à 105.

Cette deuxième Région au Canada vous permet d’élaborer des infrastructures multi-Régions qui demeurent disponibles 99,999 % du temps, tout en conservant vos données à l’intérieur des frontières canadiennes.

Une empreinte mondiale
Notre approche en matière de développement de notre infrastructure est fondamentalement différente de celle adoptée par d’autres fournisseurs. Au cœur de notre infrastructure mondiale, vous trouvez des Régions. Une Région AWS est un lieu physique dans le monde, dans lequel nous avons plusieurs Zones de disponibilité. Les Zones de disponibilité sont formées d’un ou plusieurs centres de données distincts, chacun doté de systèmes d’alimentation, de réseau et de connectivité redondants, et hébergés dans des installations séparées. Contrairement aux autres fournisseurs infonuagiques, qui définissent souvent une région comme étant un centre de données unique, le fait de pouvoir compter sur plusieurs Zones de disponibilité vous permet d’exploiter des applications et des bases de données de production ayant une plus grande disponibilité, une meilleure tolérance aux pannes et une plus importante évolutivité, allant ainsi au-delà des possibilités offertes par un centre de données unique.

AWS compte plus de 17 années d’expérience dans la mise en œuvre de son infrastructure mondiale. Il n’existe pas d’algorithme de compression pour remplacer une telle expérience, surtout lorsqu’il est question d’évolutivité, de sécurité et de performances.

Des clients canadiens de toute taille, dont des marques mondiales telles que BlackBerry, CI Financial, Keyera, KOHO, Maple Leaf Sports & Entertainment (MLSE), Nutrien, Sun Life et TELUS, ainsi que de jeunes pousses comme Good Chemistry and Cohere, en plus d’organismes du secteur public telles que l’Université de Calgary et Ressources naturelles Canada (RNCan), exécutent déjà des charges de travail sur AWS. Ces entreprises et organismes ont choisi AWS pour la sécurité, les performances, la flexibilité et la présence mondiale que nous offrons.

L’infrastructure mondiale AWS, dont font partie les Zones locales AWS et les AWS Outposts, offre à nos clients la flexibilité de déployer leurs charges de travail à proximité de leur clientèle, minimisant ainsi la latence du réseau. Par exemple, un de nos clients qui bénéfice de la flexibilité d’AWS est BrainBox AI, une jeune entreprise en croissance qui élabore des technologies de décarbonation. BrainBox AI utilise l’intelligence artificielle (IA) et l’apprentissage automatique (AA) basés dans le Nuage AWS pour aider des propriétaires d’édifice, partout au monde, à réduire les émissions liées aux systèmes de chauffage, de ventilation et de climatisation jusqu’à 40 %, et la consommation énergétique jusqu’à 25 %. L’infrastructure mondiale AWS permet à leur solution de gérer, avec une latence faible, des centaines d’immeubles dans plus de 20 pays, et ce 24 heures sur 24, sept jours sur sept.

Services disponibles
Vous pouvez déployer vos charges de travail sur n’importe laquelle des familles d’instance C5, M5, M5d, R5, C6g, C6gn, C6i, C6id, M6g, M6gd, M6i, M6id, R6d, R6i, R6id, I4i, I3en, T3 et T4g. La nouvelle Région Canada Ouest (Calgary) compte 65 services AWS, tous disponibles dès le lancement. En voici la liste, en ordre alphabétique : Amazon API Gateway, AWS AppConfig, AWS Application Auto Scaling, Amazon Aurora, Aurora PostgreSQL, AWS Batch, AWS Certificate Manager, AWS CloudFormation, Amazon CloudFront, AWS Cloud Map, AWS CloudTrail, Amazon CloudWatch, Amazon CloudWatch Events, Amazon CloudWatch Logs, AWS CodeDeploy, AWS Config, AWS Database Migration Service (AWS DMS), AWS DataSync, AWS Direct Connect, Amazon DynamoDB, Amazon Elastic Block Store (Amazon EBS), Amazon Elastic Compute Cloud (Amazon EC2), Amazon EC2 Auto Scaling, Amazon Elastic Container Registry (Amazon ECR), Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS ),  , Elastic Load Balancing,  , Elastic Load Balancing – Gateway (GWLB), Amazon EMR, Amazon EventBridge, AWS Fargate, AWS Health Dashboard, AWS Identity and Access Management (IAM), Amazon Kinesis Data Streams, AWS Key Management Service (AWS KMS), AWS Lambda, AWS Management Console, AWS Marketplace, Amazon OpenSearch Service, AWS Organizations, Amazon Redshift, AWS Resource Access Manager,   Resource Groups, Amazon Route 53, AWS Secrets Manager, AWS Security Hub, AWS Security Token Service, Service Quotas, AWS Shield Standard, Amazon Simple Notification Service (Amazon SNS), Amazon Simple Queue Service (Amazon SQS), Amazon Simple Storage Service (Amazon S3), Amazon Simple Workflow Service (Amazon SWF), AWS Site-to-Site VPN, AWS Step Functions, AWS Support API, AWS Systems Manager, AWS Trusted Advisor, VM Import/Export et AWS X-Ray.

AWS au Canada
Nous soutenons nos clients et partenaires grâce à notre infrastructure canadienne depuis décembre 2016, lorsque la première Région AWS au Canada, soit la Région AWS Canada (Centre), a été inaugurée. Au cours de cette même année, nous avons lancé des emplacements Amazon CloudFront à Toronto et Montréal afin de mieux servir vos clients dans ces régions. Actuellement, nous comptons 10 points de présence (PdP) au Canada : cinq à Toronto, quatre à Montréal et un à Vancouver. Nous avons également des équipes d’ingénieurs basées dans plusieurs villes à travers le pays.

Entre 2016 et 2021, AWS a investi plus de 2,57 milliards $ CAD (1,9 milliards $ USD) au Canada et prévoit investir jusqu’à 24,8 milliards $ CAD (18,3 milliards $ USD) dans nos deux Régions d’ici 2037. En se basant sur la méthodologie entrée-sortie et les tableaux statistiques fournies par Statistique Canada, nous estimons que les investissements prévus ajouteront 43,02 milliards $ CAD (31 milliards USD) au produit intérieur brut (PIB) du Canada et soutiendront plus de 9 300 emplois équivalents temps plein (ETP) au sein de l’économie canadienne.

En plus d’offrir les avantages d’une infrastructure de classe mondiale à nos clients, Amazon s’est engagé à atteindre une empreinte carbone nette zéro pour l’ensemble de ses activités d’ici 2040, et est en voie d’alimenter l’ensemble de ses opérations avec des énergies 100 % renouvelables d’ici 2025. En 2022, 90 % de l’électricité consommée par Amazon provenait de sources d’énergie renouvelables. En outre, AWS s’est donné comme objectif d’avoir un bilan positif en matière d’eau d’ici 2030, restituant ainsi plus d’eau aux communautés que la quantité utilisée pour ses activités directes. Amazon compte quatre projets d’énergie renouvelable au Canada, soit trois situés au sud de Calgary et un autre près d’Edmonton. Selon BloombergNEF, Amazon est la plus grande entreprise acheteuse d’énergie renouvelable au pays (et au monde). Ces projets génèrent plus de 2,3 millions de mégawattheures (MWh) d’énergie propre, soit suffisamment pour alimenter 1,69 million de foyers canadiens.

La formation est également l’une de nos principales priorités. Depuis 2017, nous avons formé plus de 200 000 Canadiens et Canadiennes en compétences infonuagiques par le biais de programmes de formation et certification AWS gratuits et payants. Des apprenants ayant différents niveaux de compétences, de responsabilités et d’expérience peuvent acquérir des connaissances et des compétences pratiques grâce à AWS Skills Builder, qui offre plus de 600 cours en ligne gratuits en jusqu’à 14 langues. Amazon s’est engagé à offrir des formations gratuites en compétences infonuagiques à 29 millions de personnes à travers le monde d’ici 2025.

Sécurité
Des clients du monde entier font confiance à AWS pour assurer la sécurité de leurs données, alors que la sécurisation et la confidentialité de leurs charges de travail sont des éléments fondamentaux de notre mode de fonctionnement. Depuis les tous débuts d’AWS, nous innovons sans relâche en matière de sécurité, d’outils de protection de la vie privée et de pratiques afin de répondre aux attentes de nos clients, et même dépasser ces attentes.

Par exemple, les décisions concernant l’emplacement de stockage de vos données, et qui peut y accéder, vous appartiennent. Des services tels qu’AWS CloudTrail vous permettent de vérifier comment et quand les données sont consultées. Notre technologie de virtualisation, AWS Nitro System, a été conçue pour restreindre l’accès de tout opérateur aux données de la clientèle. Cela signifie qu’aucun membre du personnel d’AWS, ou même un service AWS, peut accéder aux données lorsqu’elles sont utilisées au sein d’une instance Amazon Elastic Compute Cloud (Amazon EC2). En effet, NCC Group, une des principales firmes de conseil en cybersécurité au Royaume‑Uni, a procédé à une vérification de notre architecture Nitro et a confirmé nos affirmations.

Notre infrastructure de base est conçue pour répondre aux exigences de sécurité des armées, des banques mondiales, ainsi que d’autres organisations traitant des informations hautement sensibles.

Basée au Canada, Neo est une jeune pousse spécialisée en technologie financière qui profite de l’élasticité du Nuage AWS pour développer ses activités. En 2019, l’entreprise a choisi AWS car nous l’avions aidée à répondre aux exigences réglementaires du secteur. Elle utilise Amazon Elastic Compute Cloud (Amazon EC2) pour son infrastructure de base, Amazon Simple Storage Service (Amazon S3) pour un stockage très durable, Amazon GuardDuty pour améliorer sa posture de sécurité, ainsi qu’Amazon CloudFront afin d’optimiser les performances de ses systèmes pour sa clientèle.

Performances
L’infrastructure mondiale AWS est conçue pour offrir les meilleures performances et la plus faible latence atteignable, minimiser la perte de paquets et fournir la meilleure qualité générale pour l’ensemble du réseau. Cela est rendu possible grâce à un réseau dorsal de fibre optique de 400 GbE entièrement redondant, permettant souvent plusieurs térabits de capacité entre les Régions.

Afin d’offrir une latence encore plus faible à nos clients canadiens, nous avons annoncé la mise en place de deux Zone locales AWS à Toronto et Vancouver.

Les performances sont davantage importantes lorsque vous visionnez la diffusion en continu de votre émission préférée. L’entreprise Kidoodle.TV, basée à Calgary, offre un service de diffusion en continu destiné aux enfants. Elle compte plus de 100 millions de téléchargements de son application à travers le monde et plus d’un milliard de secondes publicitaires à vendre par période de 48 heures. En utilisant AWS, Kidoodle.TV a pu mettre en place le même type d’architecture de service que les entreprises multimilliardaires sont en mesure de déployer. Cela a permis à l’entreprise de passer, en une année, de 400 000 à 1,2 million d’utilisateurs actifs mensuels.

Informations complémentaires
Nous avons annoncé 12 futures Zones de disponibilité dans quatre Régions additionnelles en Malaisie, en Nouvelle‑Zélande, en Thaïlande et la Région souveraine en Europe; nous aurons le plaisir de partager des informations supplémentaires le moment venu.

Je suis impatient de découvrir vos innovations ainsi que les extraordinaires services que vous allez mettre en œuvre au sein de la Région AWS Canada Ouest (Calgary). N’hésitez pas à développer et à déployer votre infrastructure sur ca‑west‑1 dès aujourd’hui.

— Seb

AWS Weekly Roundup — AWS Lambda, AWS Amplify, Amazon OpenSearch Service, Amazon Rekognition, and more — December 18, 2023

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-lambda-aws-amplify-amazon-opensearch-service-amazon-rekognition-and-more-december-18-2023/

My memories of Amazon Web Services (AWS) re:Invent 2023 are still fresh even when I’m currently wrapping up my activities in Jakarta after participating in AWS Community Day Indonesia. It was a great experience, from delivering chalk talks and having thoughtful discussions with AWS service teams, to meeting with AWS Heroes, AWS Community Builders, and AWS User Group leaders. AWS re:Invent brings the global AWS community together to learn, connect, and be inspired by innovation. For me, that spirit of connection is what makes AWS re:Invent always special.
Here’s a quick look of my highlights at AWS re:Invent and AWS Community Day Indonesia:

If you missed AWS re:Invent, you can watch the keynotes and sessions on demand. Also, check out the AWS News Editorial Team’s Top announcements of AWS re:Invent 2023 for all the major launches.

Recent AWS launches
Here are some of the launches that caught my attention in the past two weeks:

Query MySQL and PostgreSQL with AWS Amplify – In this post, Channy wrote how you can now connect your MySQL and PostgreSQL databases to AWS Amplify with just a few clicks. It generates a GraphQL API to query your database tables using AWS CDK.

Migration Assistant for Amazon OpenSearch Service – With this self-service solution, you can smoothly migrate from your self-managed clusters to Amazon OpenSearch Service managed clusters or serverless collections.

AWS Lambda simplifies connectivity to Amazon RDS and RDS Proxy – Now you can connect your AWS Lambda to Amazon RDS or RDS proxy using the AWS Lambda console. With a guided workflow, this improvement helps to minimize complexities and efforts to quickly launch a database instance and correctly connect a Lambda function.

New no-code dashboard application to visualize IoT data – With this announcement, you can now visualize and interact with operational data from AWS IoT SiteWise using a new open source Internet of Things (IoT) dashboard.

Amazon Rekognition improves Face Liveness accuracy and user experience – This launch provides higher accuracy in detecting spoofed faces for your face-based authentication applications.

AWS Lambda supports additional concurrency metrics for improved quota monitoring – Add CloudWatch metrics for your Lambda quotas, to improve visibility into concurrency limits.

AWS Malaysia now supports 3D-Secure authentication – This launch enables 3DS2 transaction authentication required by banks and payment networks, facilitating your secure online payments.

Announcing AWS CloudFormation template generation for Amazon EventBridge Pipes – With this announcement, you can now streamline the deployment of your EventBridge resources with CloudFormation templates, accelerating event-driven architecture (EDA) development.

Enhanced data protection for CloudWatch Logs – With the enhanced data protection, CloudWatch Logs helps identify and redact sensitive data in your logs, preventing accidental exposure of personal data.

Send SMS via Amazon SNS in Asia Pacific – With this announcement, now you can use SMS messaging across Asia Pacific from the Jakarta Region.

Lambda adds support for Python 3.12 – This launch brings the latest Python version to your Lambda functions.

CloudWatch Synthetics upgrades Node.js runtime – Now you can use Node.js 16.1 runtimes for your canary functions.

Manage EBS Volumes for your EC2 fleets – This launch simplifies attaching and managing EBS volumes across your EC2 fleets.

See you next year!
This is the last AWS Weekly Roundup for this year, and we’d like to thank you for being our wonderful readers. We’ll be back to share more launches for you on January 8, 2024.

Happy holidays!

— Donnie

New for AWS Amplify – Query MySQL and PostgreSQL database for AWS CDK

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-for-aws-amplify-query-mysql-and-postgresql-database-for-aws-cdk/

Today we are announcing the general availability to connect and query your existing MySQL and PostgreSQL databases with support for AWS Cloud Development Kit (AWS CDK), a new feature to create a real-time, secure GraphQL API for your relational database within or outside Amazon Web Services (AWS). You can now generate the entire API for all relational database operations with just your database endpoint and credentials. When your database schema changes, you can run a command to apply the latest table schema changes.

In 2021, we announced AWS Amplify GraphQL Transformer version 2, enabling developers to develop more feature-rich, flexible, and extensible GraphQL-based app backends even with minimal cloud expertise. This new GraphQL Transformer was redesigned from the ground up to generate extensible pipeline resolvers to route a GraphQL API request, apply business logic, such as authorization, and communicate with the underlying data source, such as Amazon DynamoDB.

However, customers wanted to use relational database sources for their GraphQL APIs such as their Amazon RDS or Amazon Aurora databases in addition to Amazon DynamoDB. You can now use @model types of Amplify GraphQL APIs for both relational database and DynamoDB data sources. Relational database information is generated to a separate schema.sql.graphql file. You can continue to use the regular schema.graphql files to create and manage DynamoDB-backed types.

When you simply provide any MySQL or PostgreSQL database information, whether behind a virtual private cloud (VPC) or publicly accessible on the internet, AWS Amplify automatically generates a modifiable GraphQL API that securely connects to your database tables and exposes create, read, update, or delete (CRUD) queries and mutations. You can also rename your data models to be more idiomatic for the frontend. For example, a database table is called “todos” (plural, lowercase) but is exposed as “ToDo” (singular, PascalCase) to the client.

With one line of code, you can add any of the existing Amplify GraphQL authorization rules to your API, making it seamless to build use cases such as owner-based authorization or public read-only patterns. Because the generated API is built on AWS AppSync‘ GraphQL capabilities, secure real-time subscriptions are available out of the box. You can subscribe to any CRUD events from any data model with a few lines of code.

Getting started with your MySQL database in AWS CDK
The AWS CDK lets you build reliable, scalable, cost-effective applications in the cloud with the considerable expressive power of a programming language. To get started, install the AWS CDK on your local machine.

$ npm install -g aws-cdk

Run the following command to verify the installation is correct and print the version number of the AWS CDK.

$ cdk –version

Next, create a new directory for your app:

$ mkdir amplify-api-cdk
$ cd amplify-api-cdk

Initialize a CDK app by using the cdk init command.

$ cdk init app --language typescript

Install Amplify’s GraphQL API construct in the new CDK project:

$ npm install @aws-amplify/graphql-api-construct

Open the main stack file in your CDK project (usually located in lib/<your-project-name>-stack.ts). Import the necessary constructs at the top of the file:

import {
    AmplifyGraphqlApi,
    AmplifyGraphqlDefinition
} from '@aws-amplify/graphql-api-construct';

Generate a GraphQL schema for a new relational database API by executing the following SQL statement on your MySQL database. Make sure to output the results to a .csv file, including column headers, and replace <database-name> with the name of your database, schema, or both.

SELECT
  INFORMATION_SCHEMA.COLUMNS.TABLE_NAME,
  INFORMATION_SCHEMA.COLUMNS.COLUMN_NAME,
  INFORMATION_SCHEMA.COLUMNS.COLUMN_DEFAULT,
  INFORMATION_SCHEMA.COLUMNS.ORDINAL_POSITION,
  INFORMATION_SCHEMA.COLUMNS.DATA_TYPE,
  INFORMATION_SCHEMA.COLUMNS.COLUMN_TYPE,
  INFORMATION_SCHEMA.COLUMNS.IS_NULLABLE,
  INFORMATION_SCHEMA.COLUMNS.CHARACTER_MAXIMUM_LENGTH,
  INFORMATION_SCHEMA.STATISTICS.INDEX_NAME,
  INFORMATION_SCHEMA.STATISTICS.NON_UNIQUE,
  INFORMATION_SCHEMA.STATISTICS.SEQ_IN_INDEX,
  INFORMATION_SCHEMA.STATISTICS.NULLABLE
      FROM INFORMATION_SCHEMA.COLUMNS
      LEFT JOIN INFORMATION_SCHEMA.STATISTICS ON INFORMATION_SCHEMA.COLUMNS.TABLE_NAME=INFORMATION_SCHEMA.STATISTICS.TABLE_NAME AND INFORMATION_SCHEMA.COLUMNS.COLUMN_NAME=INFORMATION_SCHEMA.STATISTICS.COLUMN_NAME
      WHERE INFORMATION_SCHEMA.COLUMNS.TABLE_SCHEMA = '<database-name>';

Run the following command, replacing <path-schema.csv> with the path to the .csv file created in the previous step.

$ npx @aws-amplify/cli api generate-schema \
    --sql-schema <path-to-schema.csv> \
    --engine-type mysql –out lib/schema.sql.graphql

You can open schema.sql.graphql file to see the imported data model from your MySQL database schema.

input AMPLIFY {
     engine: String = "mysql"
     globalAuthRule: AuthRule = {allow: public}
}

type Meals @model {
     id: Int! @primaryKey
     name: String!
}

type Restaurants @model {
     restaurant_id: Int! @primaryKey
     address: String!
     city: String!
     name: String!
     phone_number: String!
     postal_code: String!
     ...
}

If you haven’t already done so, go to the Parameter Store in the AWS Systems Manager console and create a parameter for the connection details of your database, such as hostname/url, database name, port, username, and password. These will be required in the next step for Amplify to successfully connect to your database and perform GraphQL queries or mutations against it.

In the main stack class, add the following code to define a new GraphQL API. Replace the dbConnectionConfg options with the parameter paths created in the previous step.

new AmplifyGraphqlApi(this, "MyAmplifyGraphQLApi", {
  apiName: "MySQLApi",
  definition: AmplifyGraphqlDefinition.fromFilesAndStrategy(
    [path.join(__dirname, "schema.sql.graphql")],
    {
      name: "MyAmplifyGraphQLSchema",
      dbType: "MYSQL",
      dbConnectionConfig: {
        hostnameSsmPath: "/amplify-cdk-app/hostname",
        portSsmPath: "/amplify-cdk-app/port",
        databaseNameSsmPath: "/amplify-cdk-app/database",
        usernameSsmPath: "/amplify-cdk-app/username",
        passwordSsmPath: "/amplify-cdk-app/password",
      },
    }
  ),
  authorizationModes: { apiKeyConfig: { expires: cdk.Duration.days(7) } },
  translationBehavior: { sandboxModeEnabled: true },
});

This configuration assums that your database is accessible from the internet. Also, the default authorization mode is set to Api Key for AWS AppSync and the sandbox mode is enabled to allow public access on all models. This is useful for testing your API before adding more fine-grained authorization rules.

Finally, deploy your GraphQL API to AWS Cloud.

$ cdk deploy

You can now go to the AWS AppSync console and find your created GraphQL API.

Choose your project and the Queries menu. You can see newly created GraphQL APIs compatible with your tables of MySQL database, such as getMeals to get one item or listRestaurants to list all items.

For example, when you select items with fields of address, city, name, phone_number, and so on, you can see a new GraphQL query. Choose the Run button and you can see the query results from your MySQL database.

When you query your MySQL database, you can see the same results.

How to customize your GraphQL schema for your database
To add a custom query or mutation in your SQL, open the generated schema.sql.graphql file and use the @sql(statement: "") pass in parameters using the :<variable> notation.

type Query {
     listRestaurantsInState(state: String): Restaurants @sql("SELECT * FROM Restaurants WHERE state = :state;”)
}

For longer, more complex SQL queries, you can reference SQL statements in the customSqlStatements config option. The reference value must match the name of a property mapped to a SQL statement. In the following example, a searchPosts property on customSqlStatements is being referenced:

type Query {
      searchPosts(searchTerm: String): [Post]
      @sql(reference: "searchPosts")
}

Here is how the SQL statement is mapped in the API definition.

new AmplifyGraphqlApi(this, "MyAmplifyGraphQLApi", { 
    apiName: "MySQLApi",
    definition: AmplifyGraphqlDefinition.fromFilesAndStrategy( [path.join(__dirname, "schema.sql.graphql")],
    {
        name: "MyAmplifyGraphQLSchema",
        dbType: "MYSQL",
        dbConnectionConfig: {
        //	...ssmPaths,
     }, customSqlStatements: {
        searchPosts: // property name matches the reference value in schema.sql.graphql 
        "SELECT * FROM posts WHERE content LIKE CONCAT('%', :searchTerm, '%');",
     },
    }
  ),
//...
});

The SQL statement will be executed as if it were defined inline in the schema. The same rules apply in terms of using parameters, ensuring valid SQL syntax, and matching return types. Using a reference file keeps your schema clean and allows the reuse of SQL statements across fields. It is best practice for longer, more complicated SQL queries.

Or you can change a field and model name using the @refersTo directive. If you don’t provide the @refersTo directive, AWS Amplify assumes that the model name and field name exactly match the database table and column names.

type Todo @model @refersTo(name: "todos") {
     content: String
     done: Boolean
}

When you want to create relationships between two database tables, use the @hasOne and @hasMany directives to establish a 1:1 or 1:M relationship. Use the @belongsTo directive to create a bidirectional relationship back to the relationship parent. For example, you can make a 1:M relationship between a restaurant and its meals menus.

type Meals @model {
     id: Int! @primaryKey
     name: String!
     menus: [Restaurants] @hasMany(references: ["restaurant_id"])
}

type Restaurants @model {
     restaurant_id: Int! @primaryKey
     address: String!
     city: String!
     name: String!
     phone_number: String!
     postal_code: String!
     meals: Meals @belongsTo(references: ["restaurant_id"])
     ...
}

Whenever you make any change to your GraphQL schema or database schema in your DB instances, you should deploy your changes to the cloud:

Whenever you make any change to your GraphQL schema or database schema in your DB instances, you should re-run the SQL script and export to .csv step mentioned earlier in this guide to re-generate your schema.sql.graphql file and then deploy your changes to the cloud:

$ cdk deploy

To learn more, see Connect API to existing MySQL or PostgreSQL database in the AWS Amplify documentation.

Now available
The relational database support for AWS Amplify now works with any MySQL and PostgreSQL databases hosted anywhere within Amazon VPC or even outside of AWS Cloud.

Give it a try and send feedback to AWS re:Post for AWS Amplify, the GitHub repository of Amplify GraphQL API, or through your usual AWS Support contacts.

— Channy

P.S. Specially thanks to René Huangtian Brandel, a principal product manager at AWS for his contribution to write sample codes.

Use AWS Fault Injection Service to demonstrate multi-region and multi-AZ application resilience

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/use-aws-fault-injection-service-to-demonstrate-multi-region-and-multi-az-application-resilience/

AWS Fault Injection Service (FIS) helps you to put chaos engineering into practice at scale. Today we are launching new scenarios that will let you demonstrate that your applications perform as intended if an AWS Availability Zone experiences a full power interruption or connectivity from one AWS region to another is lost.

You can use the scenarios to conduct experiments that will build confidence that your application (whether single-region or multi-region) works as expected when something goes wrong, help you to gain a better understanding of direct and indirect dependencies, and test recovery time. After you have put your application through its paces and know that it works as expected, you can use the results of the experiment for compliance purposes. When used in conjunction with other parts of AWS Resilience Hub, FIS can help you to fully understand the overall resilience posture of your applications.

Intro to Scenarios
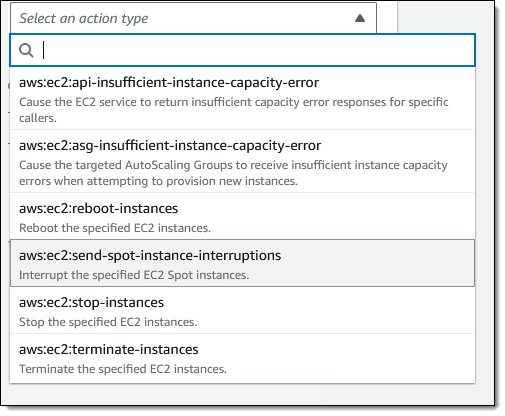
We launched FIS in 2021 to help you perform controlled experiments on your AWS applications. In the post that I wrote to announce that launch, I showed you how to create experiment templates and to use them to conduct experiments. The experiments are built using powerful, low-level actions that affect specified groups of AWS resources of a particular type. For example, the following actions operate on EC2 instances and Auto Scaling Groups:

With these actions as building blocks, we recently launched the AWS FIS Scenario Library. Each scenario in the library defines events or conditions that you can use to test the resilience of your applications:

Each scenario is used to create an experiment template. You can use the scenarios as-is, or you can take any template as a starting point and customize or enhance it as desired.

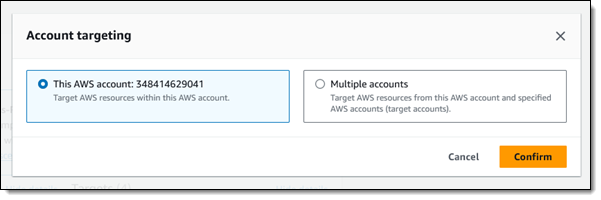
The scenarios can target resources in the same AWS account or in other AWS accounts:

New Scenarios
With all of that as background, let’s take a look at the new scenarios.

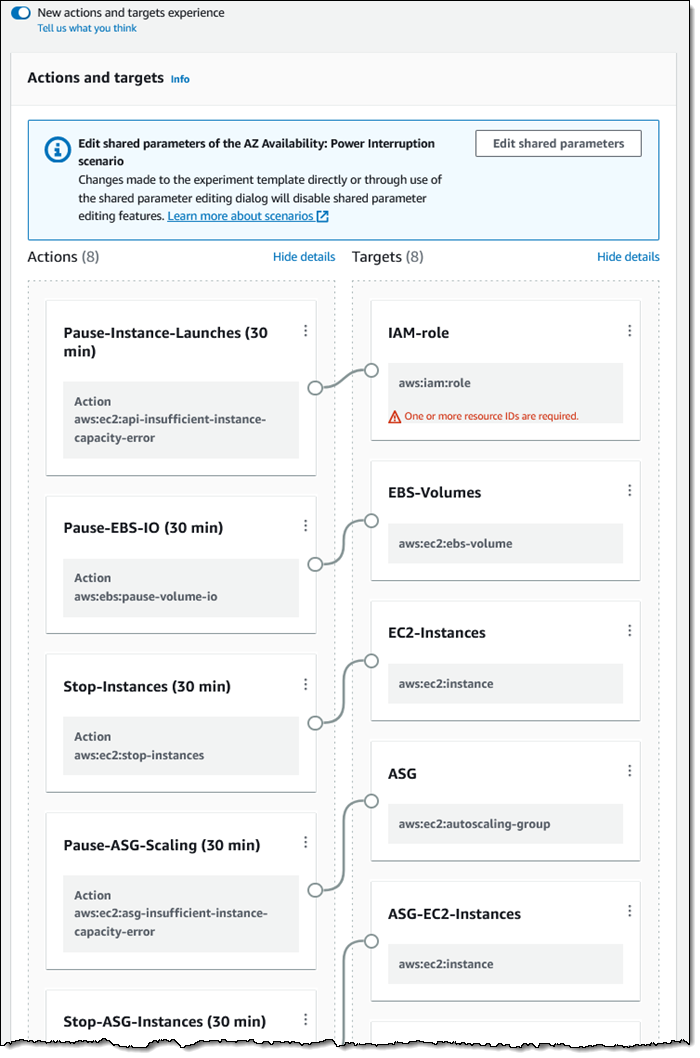
AZ Availability: Power Interruption – This scenario temporarily “pulls the plug” on a targeted set of your resources in a single Availability Zone including EC2 instances (including those in EKS and ECS clusters), EBS volumes, Auto Scaling Groups, VPC subnets, Amazon ElastiCache for Redis clusters, and Amazon Relational Database Service (RDS) clusters. In most cases you will run it on an application that has resources in more than one Availability Zone, but you can run it on a single-AZ app with an outage as the expected outcome. It targets a single AZ, and also allows you to disallow a specified set of IAM roles or Auto Scaling Groups from being able to launch fresh instances or start stopped instances during the experiment.

The New actions and targets experience makes it easy to see everything at a glance — the actions in the scenario and the types of AWS resources that they affect:

The scenarios include parameters that are used to customize the experiment template:

The Advanced parameters – targeting tags lets you control the tag keys and values that will be used to locate the resources targeted by experiments:

Cross-Region: Connectivity – This scenario prevents your application in a test region from being able to access resources in a target region. This includes traffic from EC2 instances, ECS tasks, EKS pods, and Lambda functions attached to a VPC. It also includes traffic flowing across Transit Gateways and VPC peering connections, as well as cross-region S3 and DynamoDB replication. The scenario looks like this out of the box:

This scenario runs for 3 hours (unless you change the disruptionDuration parameter), and isolates the test region from the target region in the specified ways, with advanced parameters to control the tags that are used to select the affected AWS resources in the isolated region:

You might also find that the Disrupt and Pause actions used in this scenario useful on their own:

For example, the aws:s3:bucket-pause-replication action can be used to pause replication within a region.

Things to Know
Here are a couple of things to know about the new scenarios:

Regions – The new scenarios are available in all commercial AWS Regions where FIS is available, at no additional cost.

Pricing – You pay for the action-minutes consumed by the experiments that you run; see the AWS Fault Injection Service Pricing Page for more info.

Naming – This service was formerly called AWS Fault Injection Simulator.

— Jeff;

Zonal autoshift – Automatically shift your traffic away from Availability Zones when we detect potential issues

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/zonal-autoshift-automatically-shift-your-traffic-away-from-availability-zones-when-we-detect-potential-issues/

Today we’re launching zonal autoshift, a new capability of Amazon Route 53 Application Recovery Controller that you can enable to automatically and safely shift your workload’s traffic away from an Availability Zone when AWS identifies a potential failure affecting that Availability Zone and shift it back once the failure is resolved.

When deploying resilient applications, you typically deploy your resources across multiple Availability Zones in a Region. Availability Zones are distinct groups of physical data centers at a meaningful distance apart (typically miles) to make sure that they have diverse power, connectivity, network devices, and flood plains.

To help you protect against an application’s errors, like a failed deployment, an error of configuration, or an operator error, we introduced last year the ability to manually or programmatically trigger a zonal shift. This enables you to shift the traffic away from one Availability Zone when you observe degraded metrics in that zone. It does so by configuring your load balancer to direct all new connections to infrastructure in healthy Availability Zones only. This allows you to preserve your application’s availability for your customers while you investigate the root cause of the failure. Once fixed, you stop the zonal shift to ensure the traffic is distributed across all zones again.

Zonal shift works at the Application Load Balancer (ALB) or Network Load Balancer (NLB) level only when cross-zone load balancing is turned off, which is the default for NLB. In a nutshell, load balancers offer two levels of load balancing. The first level is configured in the DNS. Load balancers expose one or more IP addresses for each Availability Zone, offering a client-side load balancing between zones. Once the traffic hits an Availability Zone, the load balancer sends traffic to registered healthy targets, typically an Amazon Elastic Compute Cloud (Amazon EC2) instance. By default, ALBs send traffic to targets across all Availability Zones. For zonal shift to properly work, you must configure your load balancers to disable cross-zone load balancing.

When zonal shift starts, the DNS sends all traffic away from one Availability Zone, as illustrated by the following diagram.

ARC Zonal Shift

Manual zonal shift helps to protect your workload against errors originating from your side. But when there is a potential failure in an Availability Zone, it is sometimes difficult for you to identify or detect the failure. Detecting an issue in an Availability Zone using application metrics is difficult because, most of the time, you don’t track metrics per Availability Zone. Moreover, your services often call dependencies across Availability Zone boundaries, resulting in errors seen in all Availability Zones. With modern microservice architectures, these detection and recovery steps must often be performed across tens or hundreds of discrete microservices, leading to recovery times of multiple hours.

Customers asked us if we could take the burden off their shoulders to detect a potential failure in an Availability Zone. After all, we might know about potential issues through our internal monitoring tools before you do.

With this launch, you can now configure zonal autoshift to protect your workloads against potential failure in an Availability Zone. We use our own AWS internal monitoring tools and metrics to decide when to trigger a network traffic shift. The shift starts automatically; there is no API to call. When we detect that a zone has a potential failure, such as a power or network disruption, we automatically trigger an autoshift of your infrastructure’s NLB or ALB traffic, and we shift the traffic back when the failure is resolved.

Obviously, shifting traffic away from an Availability Zone is a delicate operation that must be carefully prepared. We built a series of safeguards to ensure we don’t degrade your application availability by accident.

First, we have internal controls to ensure we shift traffic away from no more than one Availability Zone at a time. Second, we practice the shift on your infrastructure for 30 minutes every week. You can define blocks of time when you don’t want the practice to happen, for example, 08:00–18:00, Monday through Friday. Third, you can define two Amazon CloudWatch alarms to act as a circuit breaker during the practice run: one alarm to prevent starting the practice run at all and one alarm to monitor your application health during a practice run. When either alarm triggers during the practice run, we stop it and restore traffic to all Availability Zones. The state of application health alarm at the end of the practice run indicates its outcome: success or failure.

According to the principle of shared responsibility, you have two responsibilities as well.

First you must ensure there is enough capacity deployed in all Availability Zones to sustain the increase of traffic in remaining Availability Zones after traffic has shifted. We strongly recommend having enough capacity in remaining Availability Zones at all times and not relying on scaling mechanisms that could delay your application recovery or impact its availability. When zonal autoshift triggers, AWS Auto Scaling might take more time than usual to scale your resources. Pre-scaling your resource ensures a predictable recovery time for your most demanding applications.

Let’s imagine that to absorb regular user traffic, your application needs six EC2 instances across three Availability Zones (2×3 instances). Before configuring zonal autoshift, you should ensure you have enough capacity in the remaining Availability Zones to absorb the traffic when one Availability Zone is not available. In this example, it means three instances per Availability Zone (3×3 = 9 instances with three Availability Zones in order to keep 2×3 = 6 instances to handle the load when traffic is shifted to two Availability Zones).

In practice, when operating a service that requires high reliability, it’s normal to operate with some redundant capacity online for eventualities such as customer-driven load spikes, occasional host failures, etc. Topping up your existing redundancy in this way both ensures you can recover rapidly during an Availability Zone issue but can also give you greater robustness to other events.

Second, you must explicitly enable zonal autoshift for the resources you choose. AWS applies zonal autoshift only on the resources you chose. Applying a zonal autoshift will affect the total capacity allocated to your application. As I just described, your application must be prepared for that by having enough capacity deployed in the remaining Availability Zones.

Of course, deploying this extra capacity in all Availability Zones has a cost. When we talk about resilience, there is a business tradeoff to decide between your application availability and its cost. This is another reason why we apply zonal autoshift only on the resources you select.

Let’s see how to configure zonal autoshift
To show you how to configure zonal autoshift, I deploy my now-famous TicTacToe web application using a CDK script. I open the Route 53 Application Recovery Controller page of the AWS Management Console. On the left pane, I select Zonal autoshift. Then, on the welcome page, I select Configure zonal autoshift for a resource.

Zonal autoshift - 1

I select the load balancer of my demo application. Remember that currently, only load balancers with cross-zone load balancing turned off are eligible for zonal autoshift. As the warning on the console reminds me, I also make sure my application has enough capacity to continue to operate with the loss of one Availability Zone.

Zonal autoshift - 2

I scroll down the page and configure the times and days I don’t want AWS to run the 30-minute practice. At first, and until I’m comfortable with autoshift, I block the practice 08:00–18:00, Monday through Friday. Pay attention that hours are expressed in UTC, and they don’t vary with daylight saving time. You may use a UTC time converter application for help. While it is safe for you to exclude business hours at the start, we recommend configuring the practice run also during your business hours to ensure capturing issues that might not be visible when there is low or no traffic on your application. You probably most need zonal autoshift to work without impact at your peak time, but if you have never tested it, how confident are you? Ideally, you don’t want to block any time at all, but we recognize that’s not always practical.

Zonal autoshift - 3

Further down on the same page, I enter the two circuit breaker alarms. The first one prevents the practice from starting. You use this alarm to tell us this is not a good time to start a practice run. For example, when there is an issue ongoing with your application or when you’re deploying a new version of your application to production. The second CloudWatch alarm gives the outcome of the practice run. It enables zonal autoshift to judge how your application is responding to the practice run. If the alarm stays green, we know all went well.

If either of these two alarms triggers during the practice run, zonal autoshift stops the practice and restores the traffic to all Availability Zones.

Finally, I acknowledge that a 30-minute practice run will run weekly and that it might reduce the availability of my application.

Then, I select Create.

Zonal autoshift - 4And that’s it.

After a few days, I see the history of the practice runs on the Zonal shift history for resource tab of the console. I monitor the history of my two circuit breaker alarms to stay confident everything is correctly monitored and configured.
ARC Zonal Shift - practice run

It’s not possible to test an autoshift itself. It triggers automatically when we detect a potential issue in an Availability Zone. I asked the service team if we could shut down an Availability Zone to test the instructions I shared in this post; they politely declined my request :-).

To test your configuration, you can trigger a manual shift, which behaves identically to an autoshift.

A few more things to know
Zonal autoshift is now available at no additional cost in all AWS Regions, except for China and GovCloud.

We recommend applying the crawl, walk, run methodology. First, you get started with manual zonal shifts to acquire confidence in your application. Then, you turn on zonal autoshift configured with practice runs outside of your business hours. Finally, you modify the schedule to include practice zonal shifts during your business hours. You want to test your application response to an event when you least want it to occur.

We also recommend that you think holistically about how all parts of your application will recover when we move traffic away from one Availability Zone and then back. The list that comes to mind (although certainly not complete) is the following.

First, plan for extra capacity as I discussed already. Second, think about possible single points of failure in each Availability Zone, such as a self-managed database running on a single EC2 instance or a microservice that leaves in a single Availability Zone, and so on. I strongly recommend using managed databases, such as Amazon DynamoDB or Amazon Aurora for applications requiring zonal shifts. These have built-in replication and fail-over mechanisms in place. Third, plan the switch back when the Availability Zone will be available again. How much time do you need to scale your resources? Do you need to rehydrate caches?

You can learn more about resilient architectures and methodologies with this great series of articles from my colleague Adrian.

Finally, remember that only load balancers with cross-zone load balancing turned off are currently eligible for zonal autoshift. To turn off cross-zone load balancing from a CDK script, you need to remove stickinessCookieDuration and add load_balancing.cross_zone.enabled=false on the target group. Here is an example with CDK and Typescript:

    // Add the auto scaling group as a load balancing
    // target to the listener.
    const targetGroup = listener.addTargets('MyApplicationFleet', {
      port: 8080,
      // for zonal shift, stickiness & cross-zones load balancing must be disabled
      // stickinessCookieDuration: Duration.hours(1),
      targets: [asg]
    });    
    // disable cross zone load balancing
    targetGroup.setAttribute("load_balancing.cross_zone.enabled", "false");

Now it’s time for you to select your applications that would benefit from zonal autoshift. Start by reviewing your infrastructure capacity in each Availability Zone and then define the circuit breaker alarms. Once you are confident your monitoring is correctly configured, go and enable zonal autoshift.

— seb

IDE extension for AWS Application Composer enhances visual modern applications development with AI-generated IaC

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/ide-extension-for-aws-application-composer-enhances-visual-modern-applications-development-with-ai-generated-iac/

Today, I’m happy to share the integrated development environment (IDE) extension for AWS Application Composer. Now you can use AWS Application Composer directly in your IDE to visually build modern applications and iteratively develop your infrastructure as code templates with Amazon CodeWhisperer.

Announced as preview at AWS re:Invent 2022 and generally available in March 2023, Application Composer is a visual builder that makes it easier for developers to visualize, design, and iterate on an application architecture by dragging, grouping, and connecting AWS services on a visual canvas. Application Composer simplifies building modern applications by providing an easy-to-use visual drag-and-drop interface and generates IaC templates in real time.

AWS Application Composer also lets you work with AWS CloudFormation resources. In September, AWS Application Composer announced support for 1000+ AWS CloudFormation resources. This provides you the flexibility to define configuration for your AWS resources at a granular level.

Building modern applications with modern tools
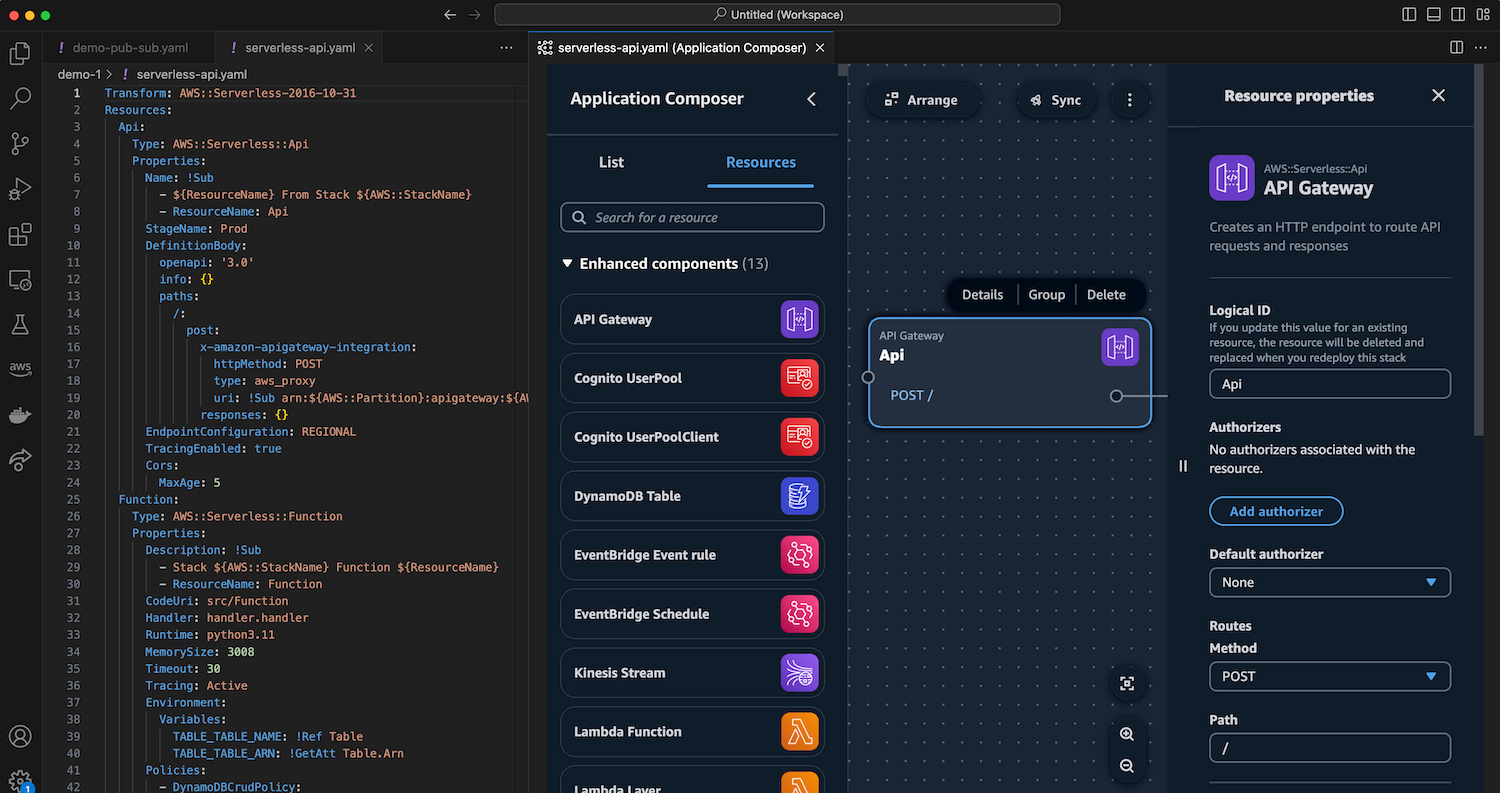
The IDE extension for AWS Application Composer provides you with the same visual drag-and-drop experience and functionality as what it offers you in the console. Utilizing the visual canvas in your IDE means you can quickly prototype your ideas and focus on your application code.

With Application Composer running in your IDE, you can also use the various tools available in your IDE. For example, you can seamlessly integrate IaC templates generated real-time by Application Composer with AWS Serverless Application Model (AWS SAM) to manage and deploy your serverless applications.

In addition to making Application Composer available in your IDE, you can create generative AI powered code suggestions in the CloudFormation template in real time while visualizing the application architecture in split view. You can pair and synchronize Application Composer’s visualization and CloudFormation template editing side by side in the IDE without context switching between consoles to iterate on their designs. This minimizes hand coding and increase your productivity.

Using AWS Application Composer in Visual Studio Code
First, I need to install the latest AWS Toolkit for Visual Studio Code plugin. If you already have the AWS Toolkit plugin installed, you only need to update the plugin to start using Application Composer.

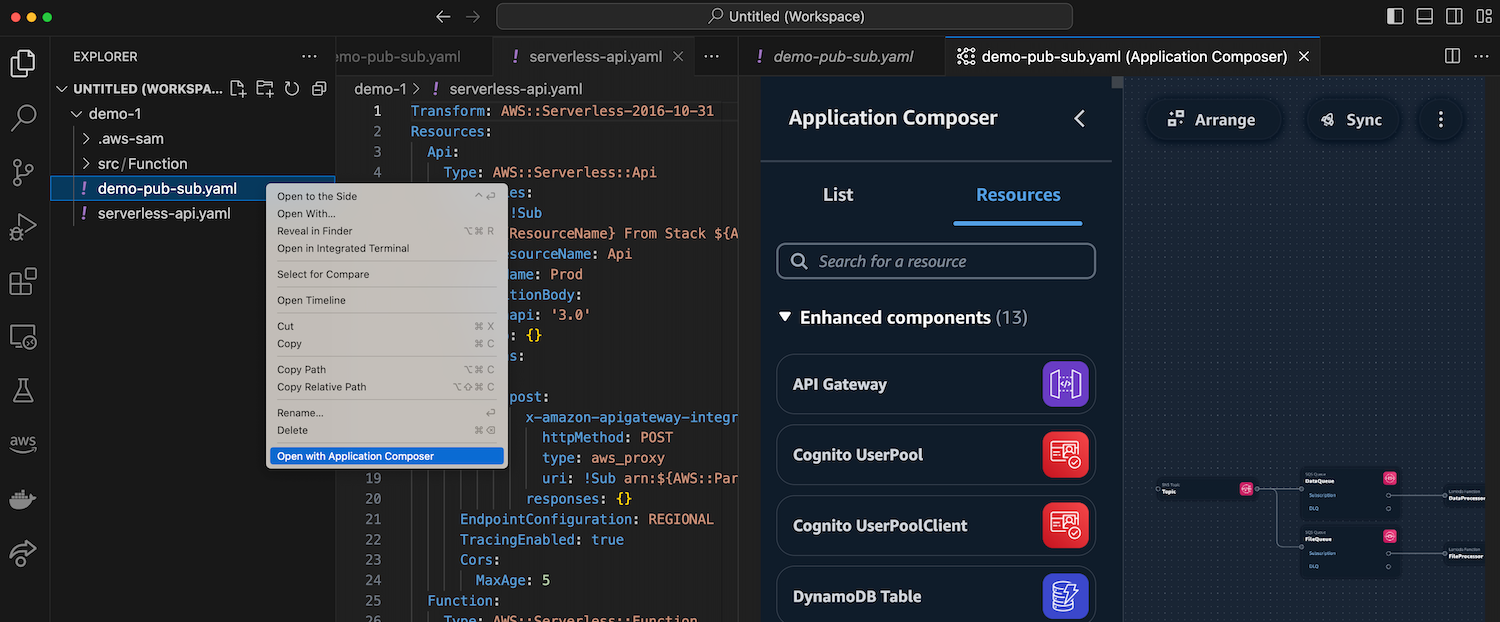
To start using Application Composer, I don’t need to authenticate into my AWS account. With Application Composer available on my IDE, I can open my existing AWS CloudFormation or AWS SAM templates.

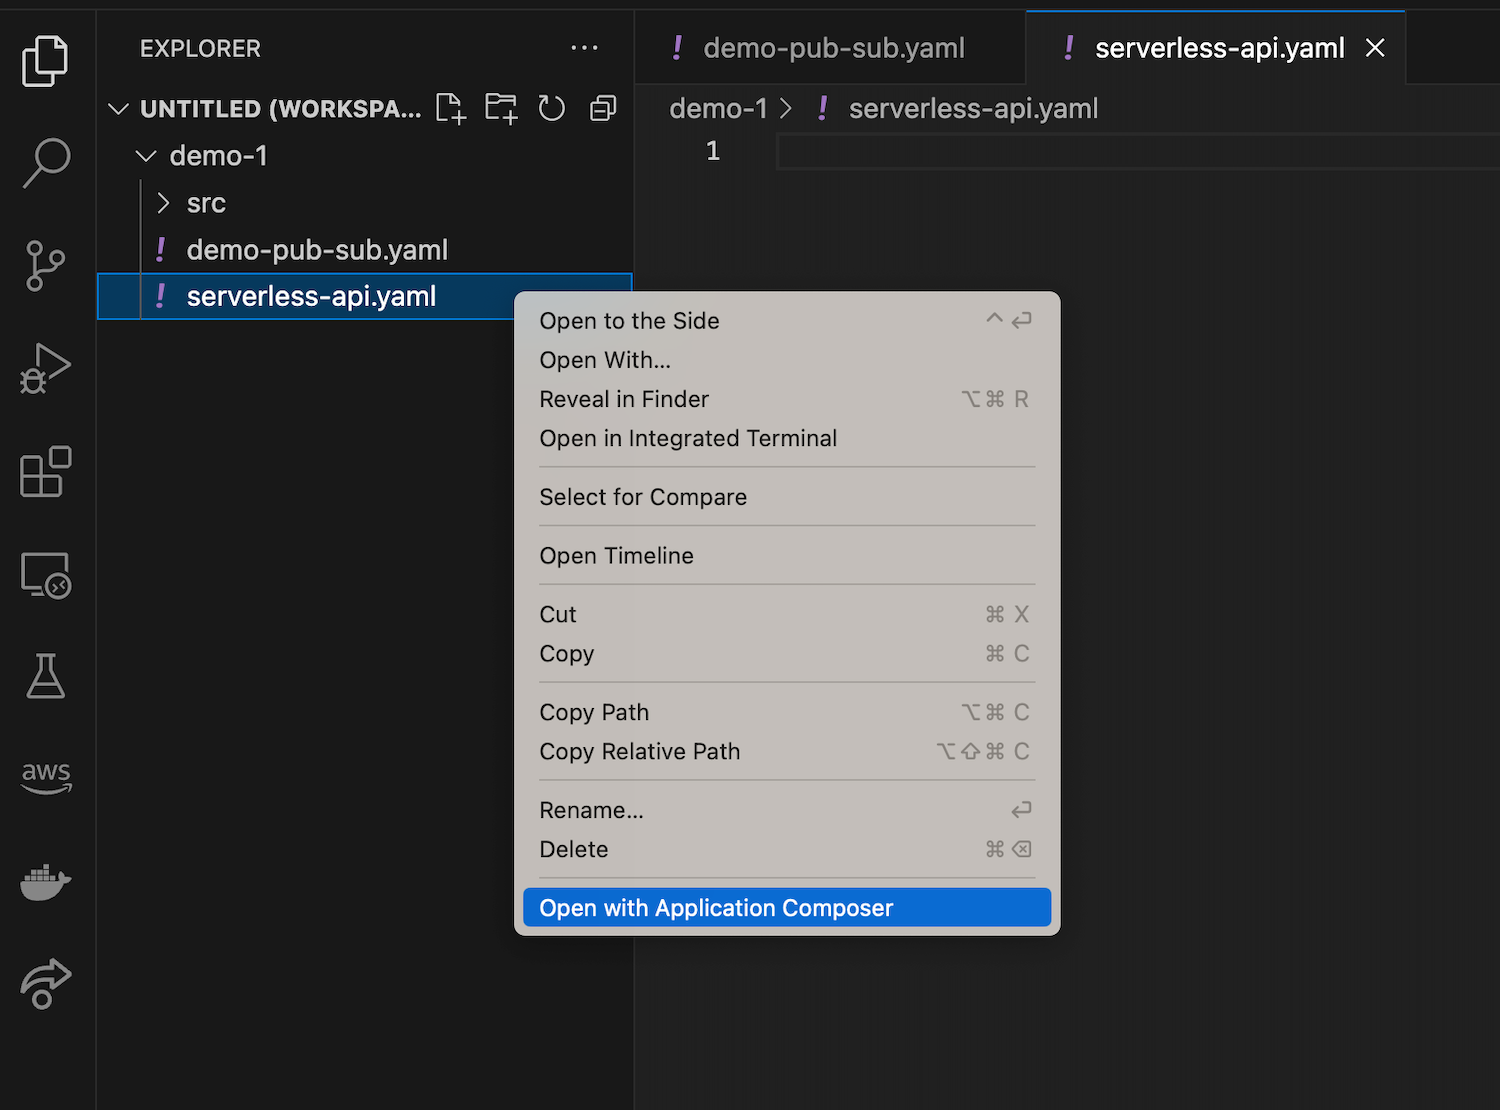
Another method is to create a new blank file, then right-click on the file and select Open with Application Composer to start designing my application visually.

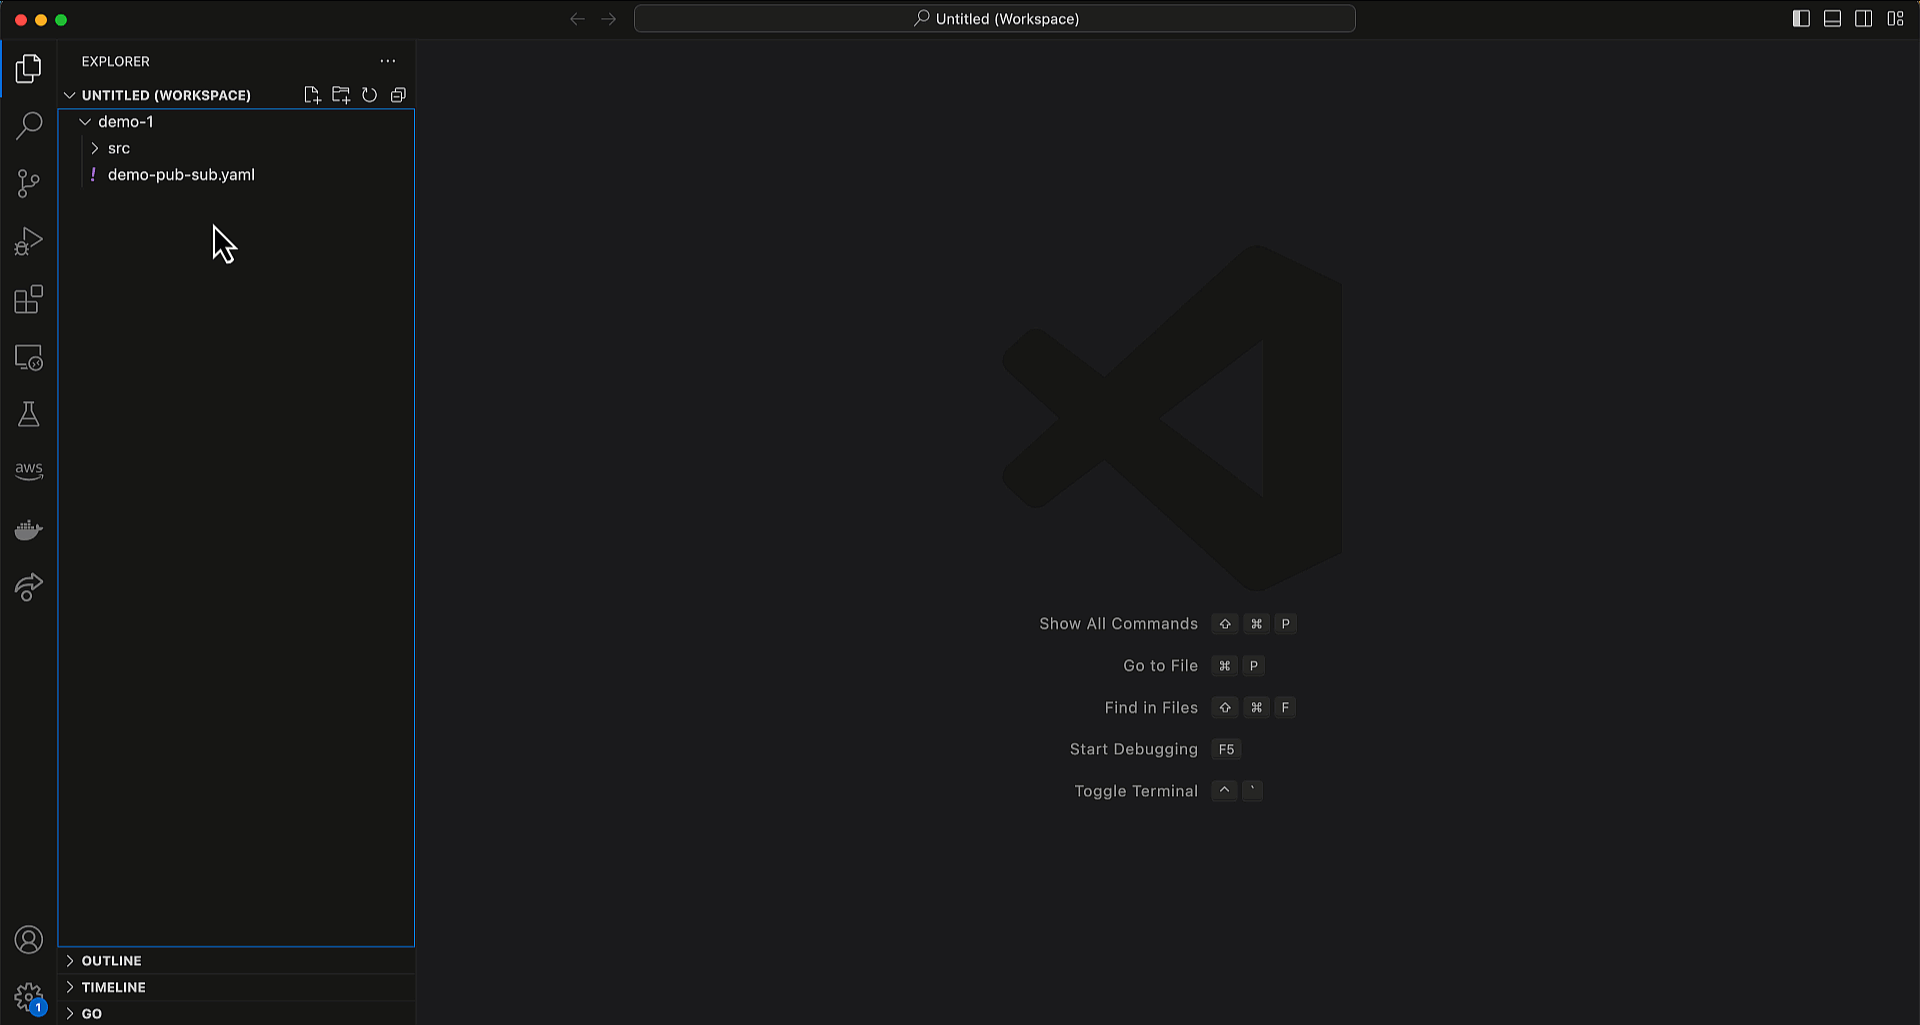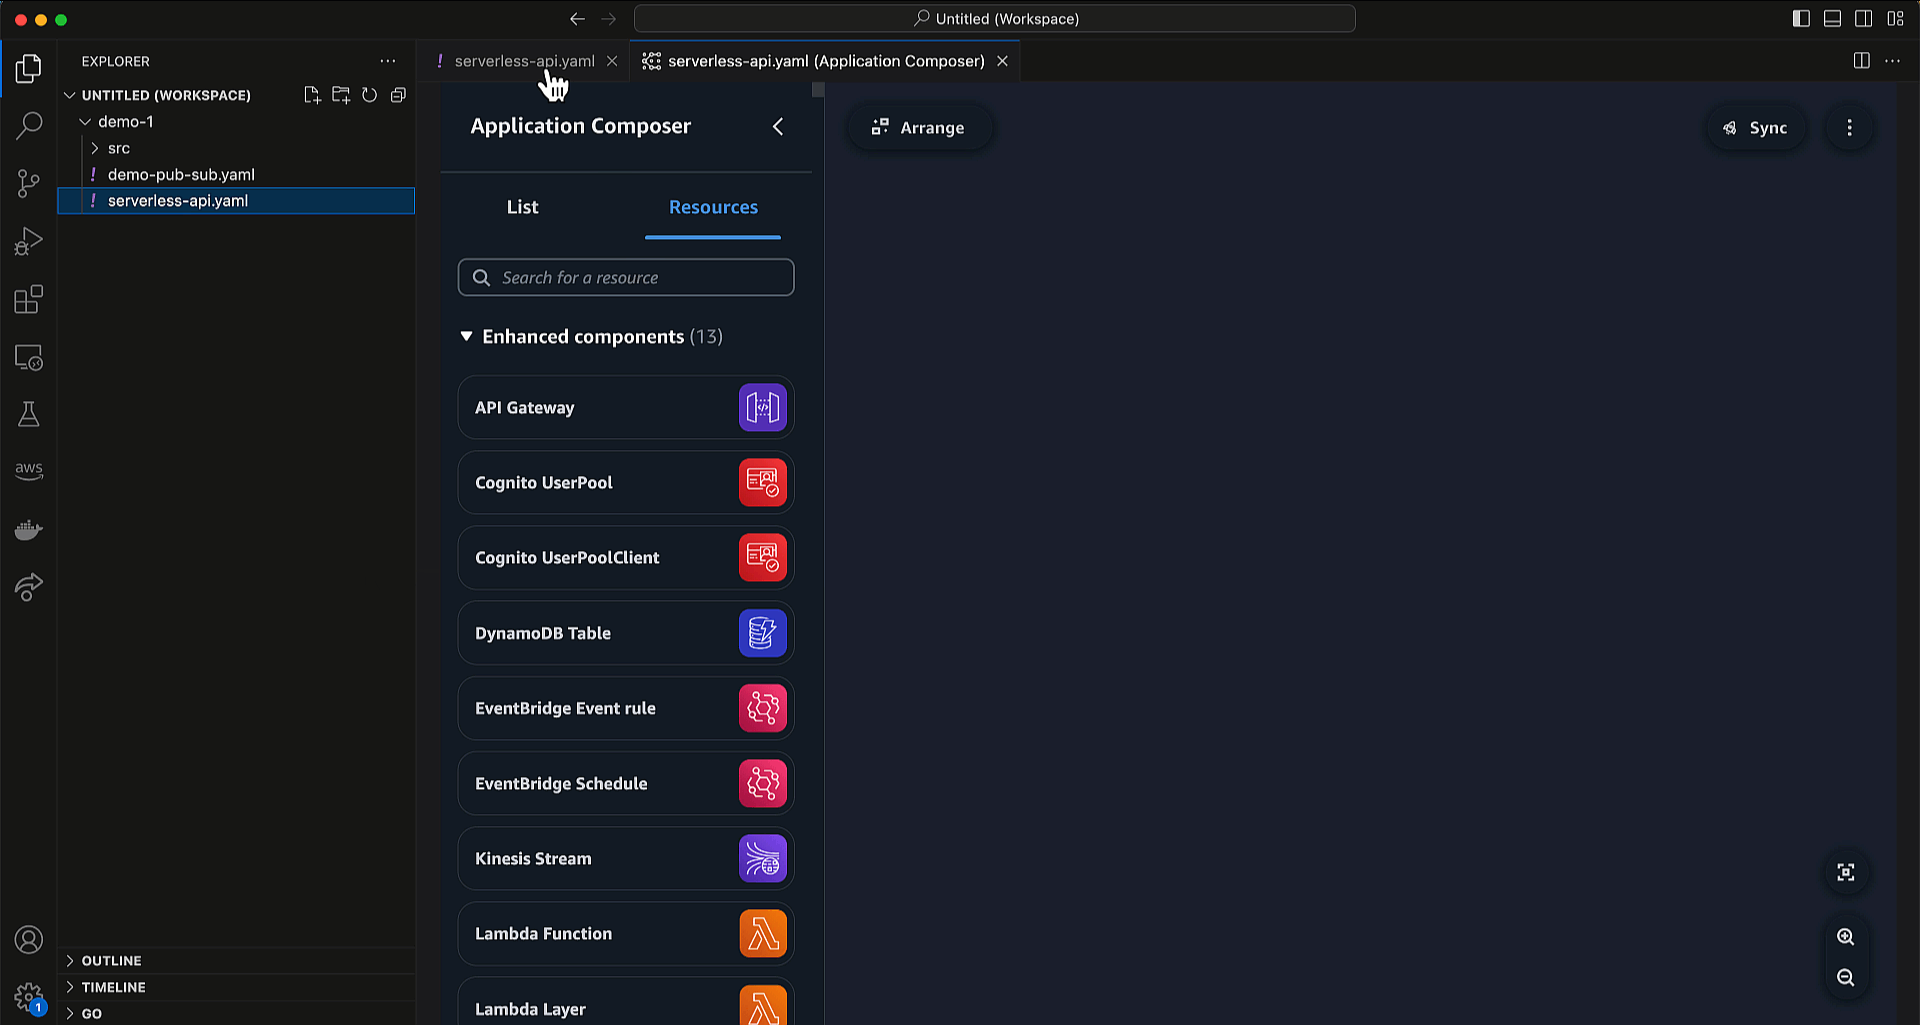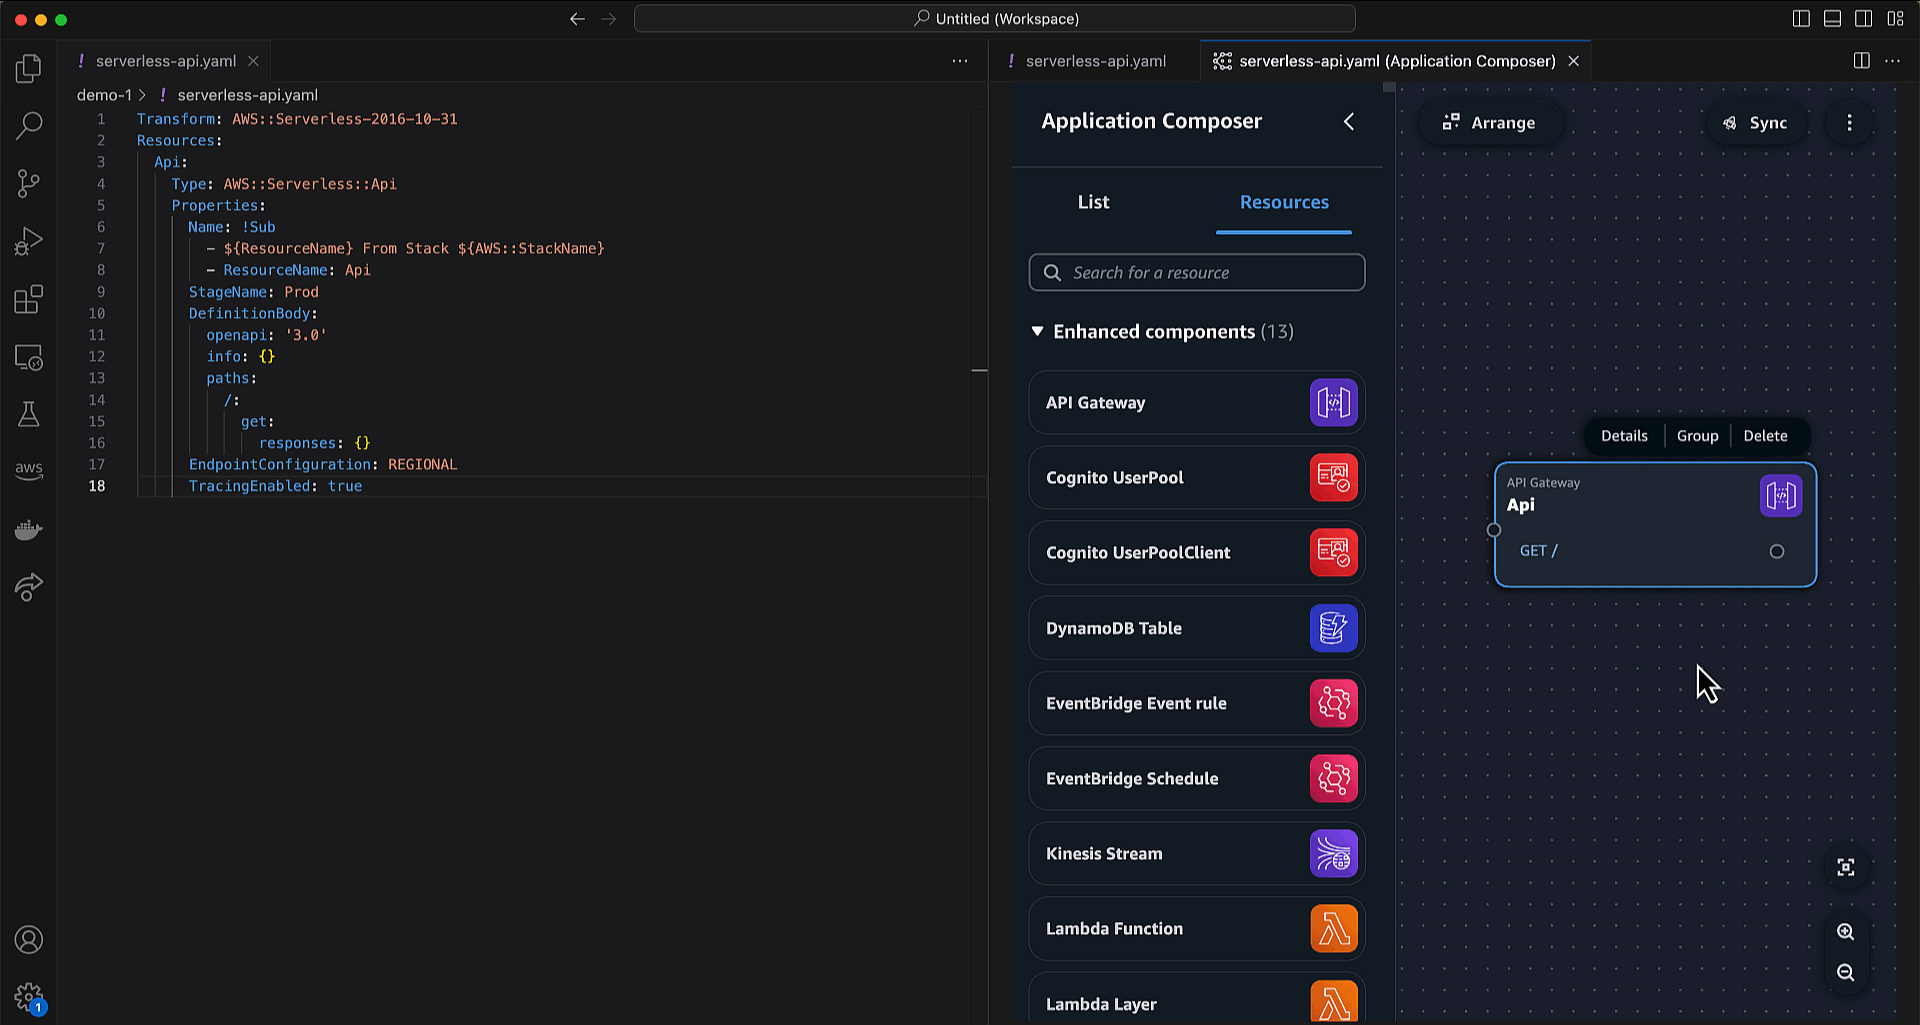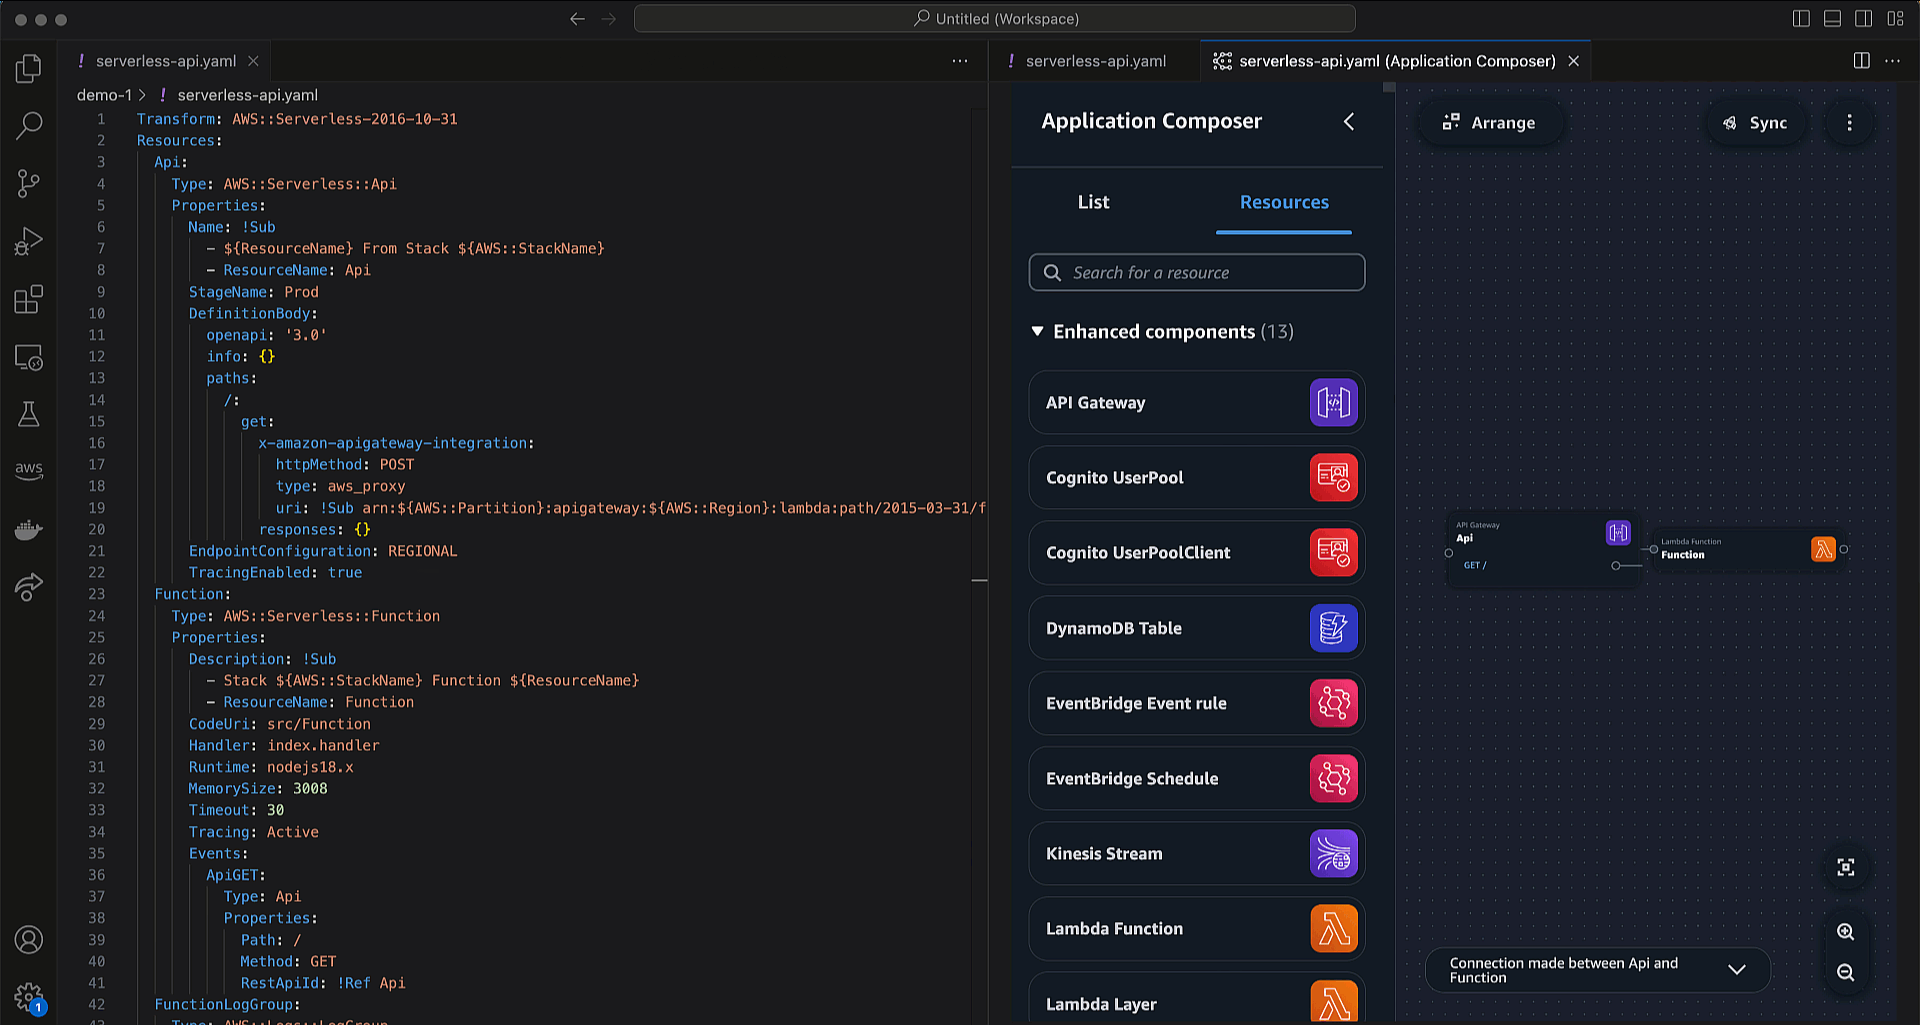
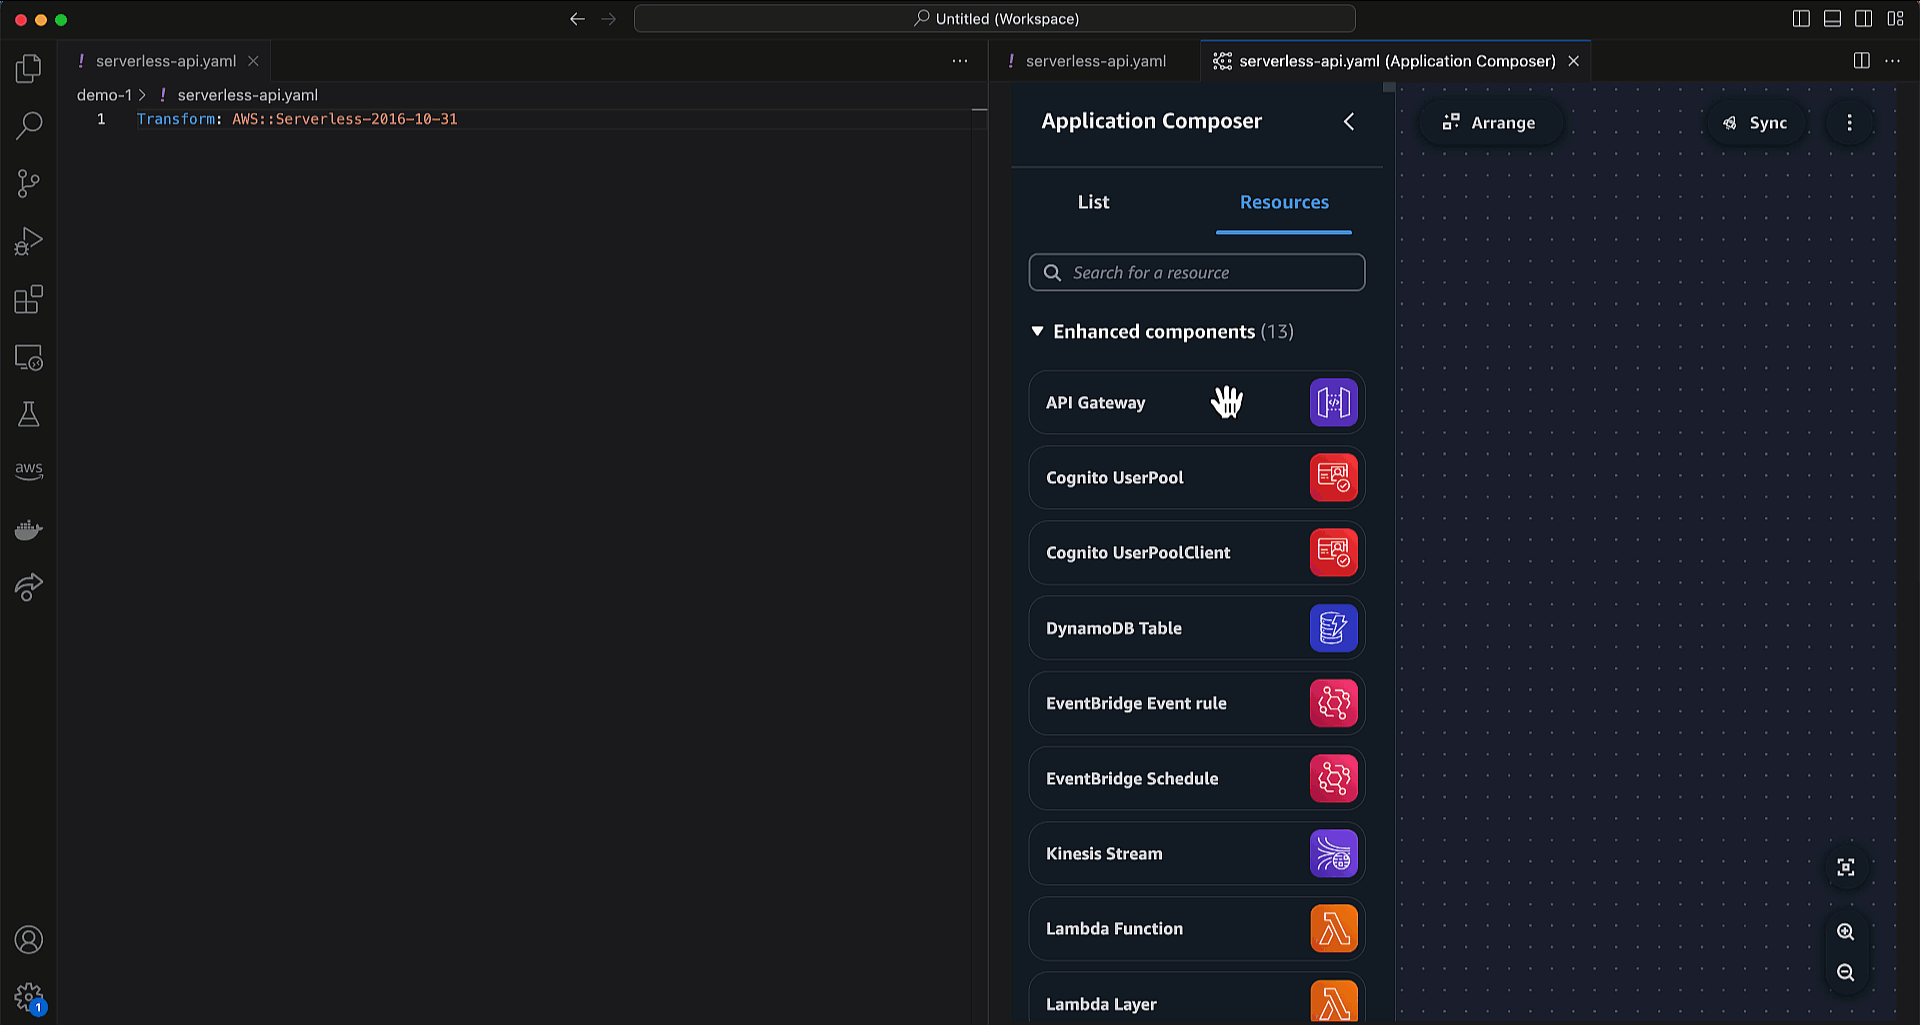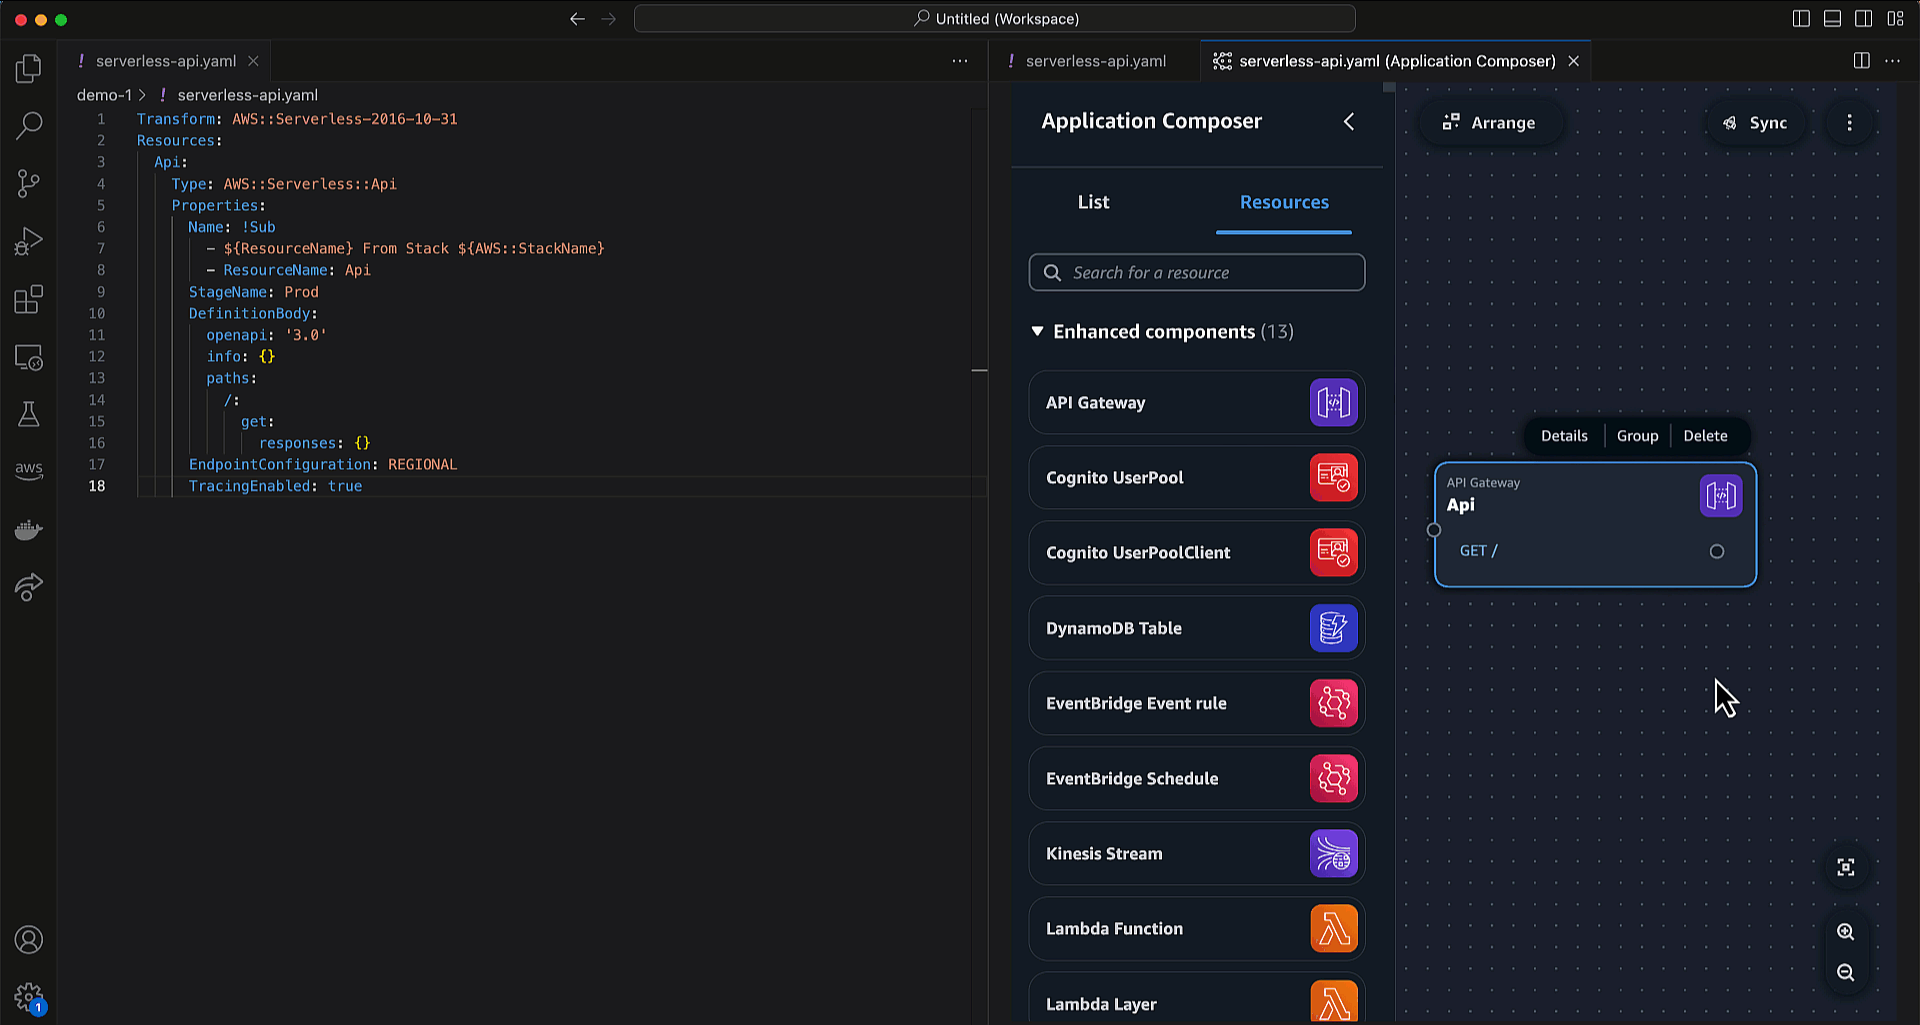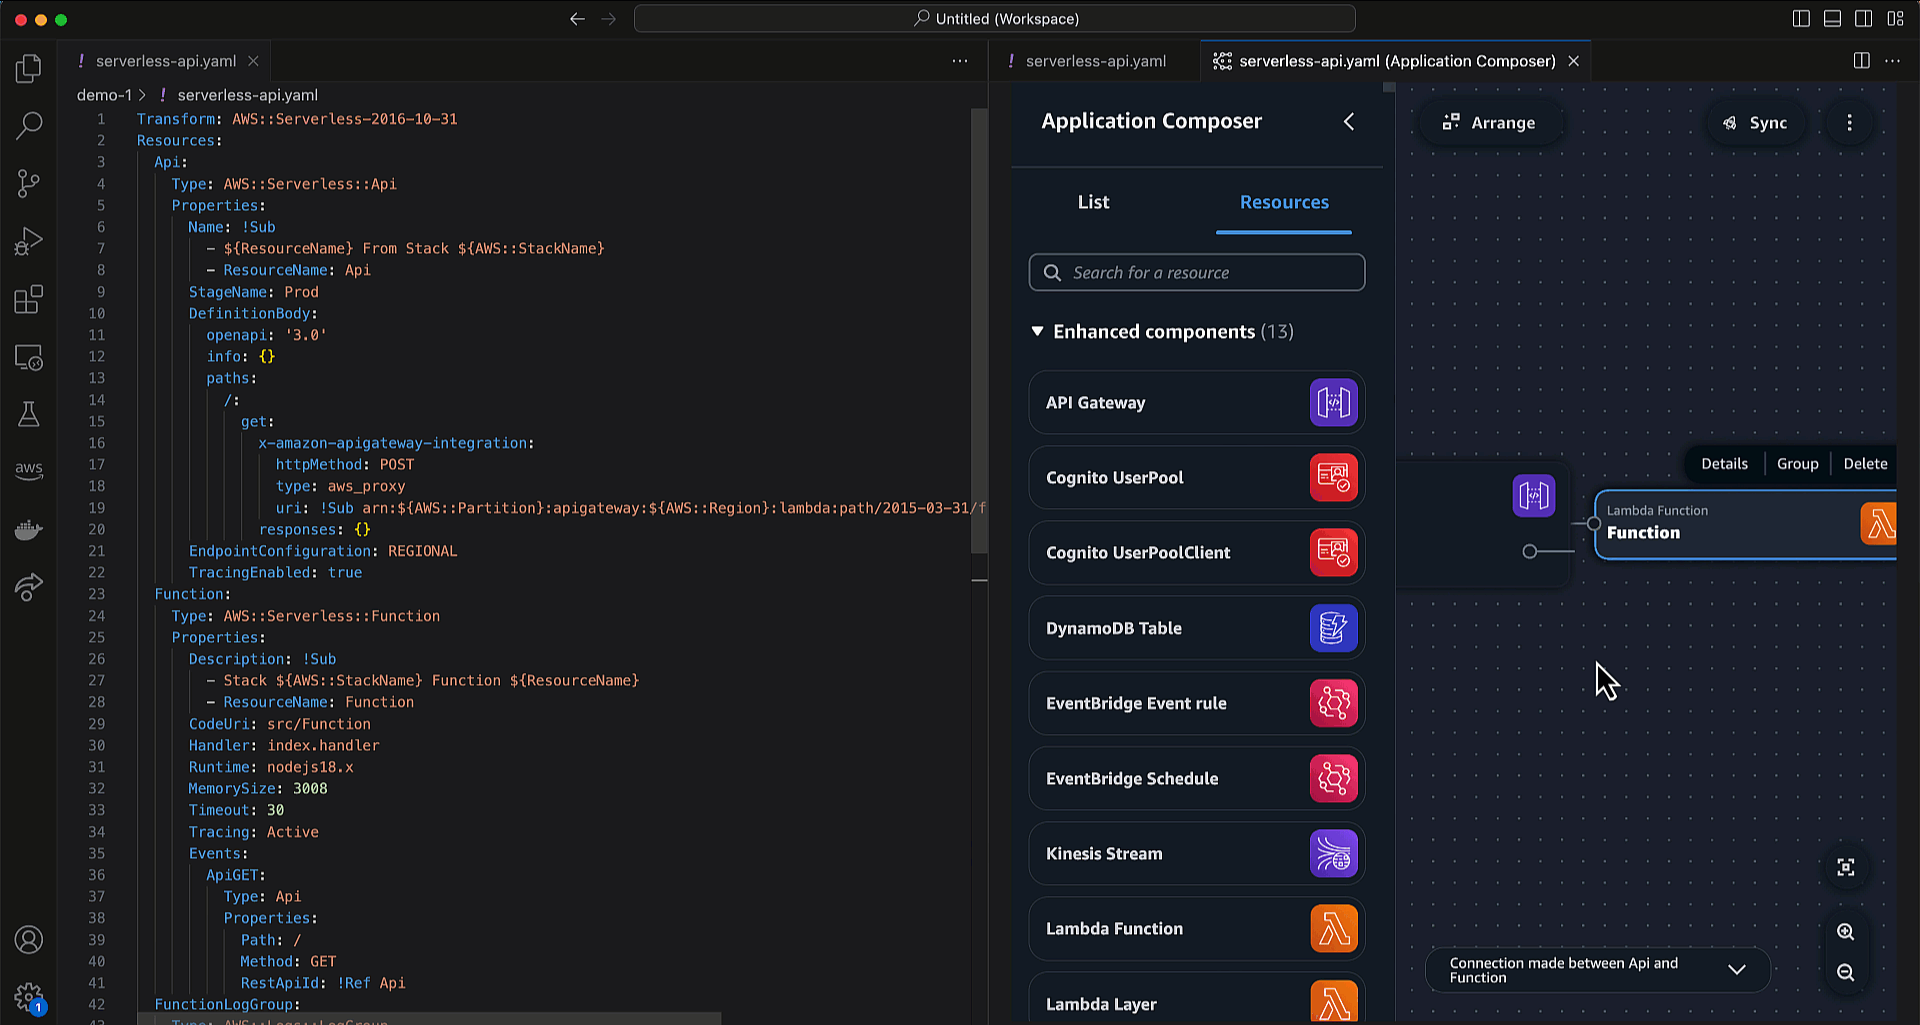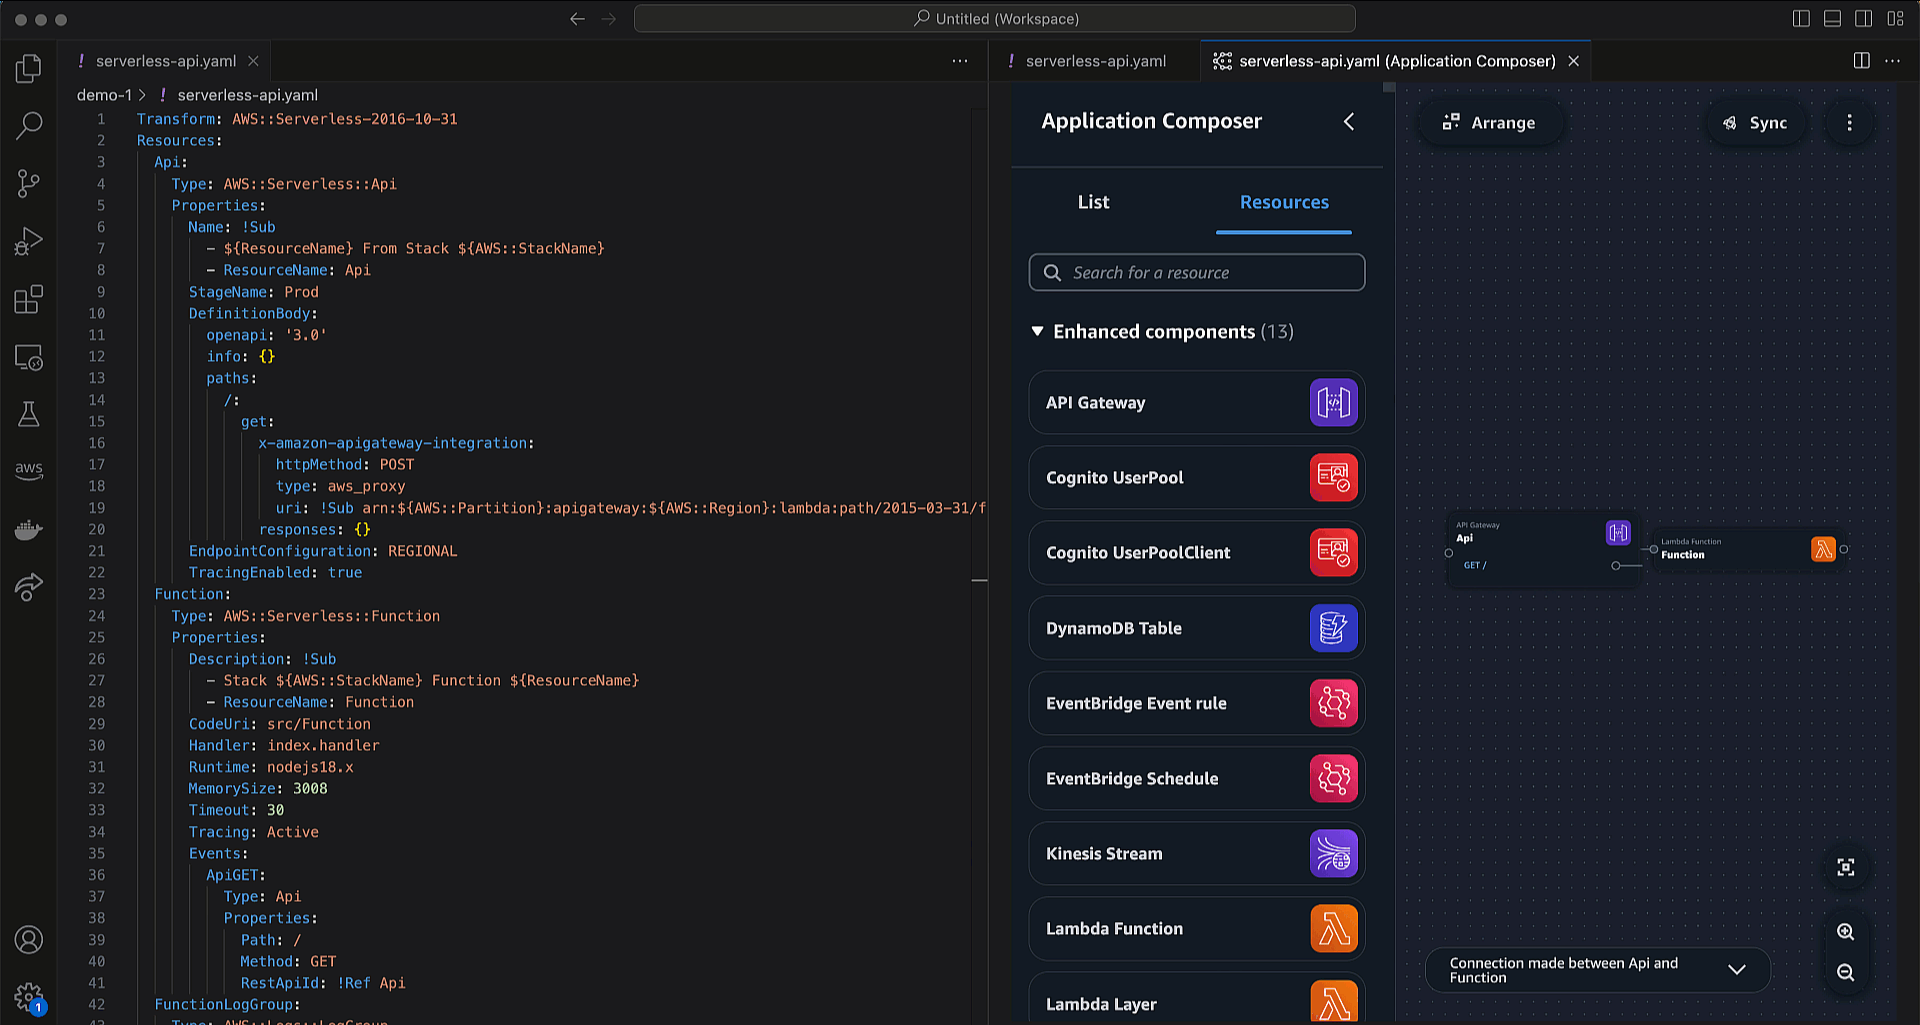
This will provide me with a blank canvas. Here I have both code and visual editors at the same time to build a simple serverless API using Amazon API Gateway, AWS Lambda, and Amazon DynamoDB. Any changes that I make on the canvas will also be reflected in real time on my IaC template.

I get consistent experiences, such as when I use the Application Composer console. For example, if I make some modifications to my AWS Lambda function, it will also create relevant files in my local folder.

With IaC templates available in my local folder, it’s easier for me to manage my applications with AWS SAM CLI. I can create continuous integration and continuous delivery (CI/CD) with sam pipeline or deploy my stack with sam deploy.

One of the features that accelerates my development workflow is the built-in Sync feature that seamlessly integrates with AWS SAM command sam sync. This feature syncs my local application changes to my AWS account, which is helpful for me to do testing and validation before I deploy my applications into a production environment.

Developing IaC templates with generative AI
With this new capability, I can use generative AI code suggestions to quickly get started with any of CloudFormation’s 1000+ resources. This also means that it’s now even easier to include standard IaC resources to extend my architecture.

For example, I need to use Amazon MQ, which is a standard IaC resource, and I need to modify some configurations for its AWS CloudFormation resource using Application Composer. In the Resource configuration section, change some values if needed, then choose Generate. Application Composer provides code suggestions that I can accept and incorporate into my IaC template.

This capability helps me to improve my development velocity by eliminating context switching. I can design my modern applications using AWS Application Composer canvas and use various tools such as Amazon CodeWhisperer and AWS SAM to accelerate my development workflow.

Things to know
Here are a couple of things to note:

Supported IDE – At launch, this new capability is available for Visual Studio Code.

Pricing – The IDE extension for AWS Application Composer is available at no charge.

Get started with IDE extension for AWS Application Composer by installing the latest AWS Toolkit for Visual Studio Code.

Happy coding!
— Donnie

Amazon SageMaker Studio adds web-based interface, Code Editor, flexible workspaces, and streamlines user onboarding

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/amazon-sagemaker-studio-adds-web-based-interface-code-editor-flexible-workspaces-and-streamlines-user-onboarding/

Today, we are announcing an improved Amazon SageMaker Studio experience! The new SageMaker Studio web-based interface loads faster and provides consistent access to your preferred integrated development environment (IDE) and SageMaker resources and tooling, irrespective of your IDE choice. In addition to JupyterLab and RStudio, SageMaker Studio now includes a fully managed Code Editor based on Code-OSS (Visual Studio Code Open Source).

Both Code Editor and JupyterLab can be launched using a flexible workspace. With spaces, you can scale the compute and storage for your IDE up and down as you go, customize runtime environments, and pause-and-resume coding anytime from anywhere. You can spin up multiple such spaces, each configured with a different combination of compute, storage, and runtimes.

SageMaker Studio now also comes with a streamlined onboarding and administration experience to help both individual users and enterprise administrators get started in minutes. Let me give you a quick tour of some of these highlights.

New SageMaker Studio web-based interface
The new SageMaker Studio web-based interface acts as a command center for launching your preferred IDE and accessing your SageMaker tools to build, train, tune, and deploy models. You can now view SageMaker training jobs and endpoints in SageMaker Studio and access foundation models (FMs) via SageMaker JumpStart. Also, you no longer need to manually upgrade SageMaker Studio.

Amazon SageMaker Studio

New Code Editor based on Code-OSS (Visual Studio Code Open Source)
As a data scientist or machine learning (ML) practitioner, you can now sign in to SageMaker Studio and launch Code Editor directly from your browser. With Code Editor, you have access to thousands of VS Code compatible extensions from Open VSX registry and the preconfigured AWS toolkit for Visual Studio Code for developing and deploying applications on AWS. You can also use the artificial intelligence (AI)-powered coding companion and security scanning tool powered by Amazon CodeWhisperer and Amazon CodeGuru.

Amazon SageMaker Studio

Launch Code Editor and JupyterLab in a flexible workspace
You can launch both Code Editor and JupyterLab using private spaces that only the user creating the space has access to. This flexible workspace is designed to provide a faster and more efficient coding environment.

The spaces come preconfigured with a SageMaker distribution that contains popular ML frameworks and Python packages. With the help of the AI-powered coding companions and security tools, you can quickly generate, debug, explain, and refactor your code.

In addition, SageMaker Studio comes with an improved collaboration experience. You can use the built-in Git integration to share and version code or bring your own shared file storage using Amazon EFS to access a collaborative filesystem across different users or teams.

Amazon SageMaker Studio

Amazon SageMaker Studio

Amazon SageMaker Studio

Streamlined user onboarding and administration
With redesigned setup and onboarding workflows, you can now set up SageMaker Studio domains within minutes. As an individual user, you can now use a one-click experience to launch SageMaker Studio using default presets and without the need to learn about domains or AWS IAM roles.

As an enterprise administrator, step-by-step instructions help you choose the right authentication method, connect to your third-party identity providers, integrate networking and security configurations, configure fine-grained access policies, and choose the right applications to enable in SageMaker Studio. You can also update settings at any time.

To get started, navigate to the SageMaker console and select either Set up for single user or Set up for organization.

Amazon SageMaker Studio

The single-user setup will start deploying a SageMaker Studio domain using default presets and will be ready within a few minutes. The setup for organizations will guide you through the configuration step-by-step. Note that you can choose to keep working with the classic SageMaker Studio experience or start exploring the new experience.

Amazon SageMaker Studio

Now available
The new Amazon SageMaker Studio experience is available today in all AWS Regions where SageMaker Studio is available. Starting today, new SageMaker Studio domains will default to the new web-based interface. If you have an existing setup and want to start using the new experience, check out the SageMaker Developer Guide for instructions on how to migrate your existing domains.

Give it a try, and let us know what you think. You can send feedback to AWS re:Post for Amazon SageMaker Studio or through your usual AWS contacts.

Start building your ML projects with Amazon SageMaker Studio today!

— Antje

Three new capabilities for Amazon Inspector broaden the realm of vulnerability scanning for workloads

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/three-new-capabilities-for-amazon-inspector-broaden-the-realm-of-vulnerability-scanning-for-workloads/

Today, Amazon Inspector adds three new capabilities to increase the realm of possibilities when scanning your workloads for software vulnerabilities:

  • Amazon Inspector introduces a new set of open source plugins and an API allowing you to assess your container images for software vulnerabilities at build time directly from your continuous integration and continuous delivery (CI/CD) pipelines wherever they are running.
  • Amazon Inspector can now continuously monitor your Amazon Elastic Compute Cloud (Amazon EC2) instances without installing an agent or additional software (in preview).
  • Amazon Inspector uses generative artificial intelligence (AI) and automated reasoning to provide assisted code remediation for your AWS Lambda functions.

Amazon Inspector is a vulnerability management service that continually scans your AWS workloads for known software vulnerabilities and unintended network exposure. Amazon Inspector automatically discovers and scans running EC2 instances, container images in Amazon Elastic Container Registry (Amazon ECR) and within your CI/CD tools, and Lambda functions.

We all know engineering teams often face challenges when it comes to promptly addressing vulnerabilities. This is because of the tight release deadlines that force teams to prioritize development over tackling issues in their vulnerability backlog. But it’s also due to the complex and ever-evolving nature of the security landscape. As a result, a study showed that organizations take 250 days on average to resolve critical vulnerabilities. It is therefore crucial to identify potential security issues early in the development lifecycle to prevent their deployment into production.

Detecting vulnerabilities in your AWS Lambda functions code
Let’s start close to the developer with Lambda functions code.

In November 2022 and June 2023, Amazon Inspector added the capability to scan your function’s dependencies and code. Today, we’re adding generative AI and automated reasoning to analyze your code and automatically create remediation as code patches.

Amazon Inspector can now provide in-context code patches for multiple classes of vulnerabilities detected during security scans. Amazon Inspector extends the assessment of your code for security issues like injection flaws, data leaks, weak cryptography, or missing encryption. Thanks to generative AI, Amazon Inspector now provides suggestions how to fix it. It shows affected code snippets in context with suggested remediation.

Here is an example. I wrote a short snippet of Python code with a hardcoded AWS secret key. Never do that!

def create_session_noncompliant():
    import boto3
    # Noncompliant: uses hardcoded secret access key.
    sample_key = "AjWnyxxxxx45xxxxZxxxX7ZQxxxxYxxx1xYxxxxx"
    boto3.session.Session(aws_secret_access_key=sample_key)
    return response

I deploy the code. This triggers the assessment. I open the AWS Management Console and navigate to the Amazon Inspector page. In the Findings section, I find the vulnerability. It gives me the Vulnerability location and the Suggested remediation in a plain natural language explanation but also in diff text and graphical formats.

Inspector automated code remediation

Detecting vulnerabilities in your container CI/CD pipeline
Now, let’s move to your CI/CD pipelines when building containers.

Until today, Amazon Inspector was able to assess container images once they were built and stored in Amazon Elastic Container Registry (Amazon ECR). Starting today, Amazon Inspector can detect security issues much sooner in the development process by assessing container images during their build within CI/CD tools. Assessment results are returned in near real-time directly to the CI/CD tool’s dashboard. There is no need to enable Amazon Inspector to use this new capability.

We provide ready-to-use CI/CD plugins for Jenkins and JetBrain’s TeamCity, with more to come. There is also a new API (inspector-scan) and command (inspector-sbomgen) available from our AWS SDKs and AWS Command Line Interface (AWS CLI). This new API allows you to integrate Amazon Inspector in the CI/CD tool of your choice.

Upon execution, the plugin runs a container extraction engine on the configured resource and generates a CycloneDX-compatible software bill of materials (SBOM). Then, the plugin sends the SBOM to Amazon Inspector for analysis. The plugin receives the result of the scan in near real-time. It parses the response and generates outputs that Jenkins or TeamCity uses to pass or fail the execution of the pipeline.

To use the plugin with Jenkins, I first make sure there is a role attached to the EC2 instance where Jenkins is installed, or I have an AWS access key and secret access key with permissions to call the Amazon Inspector API.

I install the plugin directly from Jenkins (Jenkins Dashboard > Manage Jenkins > Plugins)

Inspect CICD Install Jenkins plugin

Then, I add an Amazon Inspector Scan step in my pipeline.

Inspector CICD - add Jenkins step

I configure the step with the IAM Role I created (or an AWS access key and secret access key when running on premises), my Docker Credentials, the AWS Region, and the Image Id.

Inspector CICD - configure jenkins plugins

When Amazon Inspector detects vulnerabilities, it reports them to the plugin. The build fails, and I can view the details directly in Jenkins.

Inspector CICD - findings in jenkins

The SBOM generation understands packages or applications for popular operating systems, such as Alpine, Amazon Linux, Debian, Ubuntu, and Red Hat packages. It also detects packages for Go, Java, NodeJS, C#, PHP, Python, Ruby, and Rust programming languages.

Detecting vulnerabilities on Amazon EC2 without installing agents (in preview)
Finally, let’s talk about agentless inspection of your EC2 instances.

Currently, Amazon Inspector uses AWS Systems Manager and the AWS Systems Manager Agent (SSM Agent) to collect information about the inventory of your EC2 instances. To ensure Amazon Inspector can communicate with your instances, you have to ensure three conditions. First, a recent version of the SSM Agent is installed on the instance. Second, the SSM Agent is started. And third, you attached an IAM role to the instance to allow the SSM Agent to communicate back to the SSM service. This seems fair and simple. But it is not when considering large deployments across multiple OS versions, AWS Regions, and accounts, or when you manage legacy applications. Each instance launched that doesn’t satisfy these three conditions is a potential security gap in your infrastructure.

With agentless scanning (in preview), Amazon Inspector doesn’t require the SSM Agent to scan your instances. It automatically discovers existing and new instances and schedules a vulnerability assessment for them. It does so by taking a snapshot of the instance’s EBS volumes and analyzing the snapshot. This technique has the extra advantage of not consuming any CPU cycle or memory on your instances, leaving 100 percent of the (virtual) hardware available for your workloads. After the analysis, Amazon Inspector deletes the snapshot.

To get started, enable hybrid scanning under EC2 scanning settings in the Amazon Inspector section of the AWS Management Console. Hybrid mode means Amazon Inspector continues to use the SSM Agent–based scanning for instances managed by SSM and automatically switches to agentless for instances that are not managed by SSM.

Inspector enable hybrid scanning

Under Account management, I can verify the list of scanned instances. I can see which instances are scanned with the SSM Agent and which are not.

Inspector list of instances monitored

Under Findings, I can filter by vulnerability, by account, by instance, and so on. I select by instance and select the agentless instance I want to review.

For that specific instance, Amazon Inspector lists more than 200 findings, sorted by severity.

Inspector list of findings

As usual, I can see the details of a finding to understand what the risk is and how to mitigate it.

Inspector details of a finding

Pricing and availability
Amazon Inspector code remediation for Lambda functions is available in ten Regions: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Singapore, Sydney, Tokyo), and Europe (Frankfurt, Ireland, London, Stockholm). It is available at no additional cost.

Amazon Inspector agentless vulnerability scanning for Amazon EC2 is available in preview in three AWS Regions: US East (N. Virginia), US West (Oregon), and Europe (Ireland).

The new API to scan containers at build time is available in the 21 AWS Regions where Amazon Inspector is available today.

There are no upfront or subscription costs. We charge on-demand based on the volume of activity. There is a price per EC2 instance or container image scan. As usual, the Amazon Inspector pricing page has the details.

Start today by adding the Jenkins or TeamCity agent to your containerized application CI/CD pipelines or activate the agentless Amazon EC2 inspection.

Now go build!

— seb

New myApplications in the AWS Management Console simplifies managing your application resources

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-myapplications-in-the-aws-management-console-simplifies-managing-your-application-resources/

Today, we are announcing the general availability of myApplications supporting application operations, a new set of capabilities that help you get started with your applications on AWS, operate them with less effort, and move faster at scale. With myApplication in the AWS Management Console, you can more easily manage and monitor the cost, health, security posture, and performance of your applications on AWS.

The myApplications experience is available in the Console Home, where you can access an Applications widget that lists the applications in an account. Now, you can create your applications more easily using the Create application wizard, connecting resources in your AWS account from one view in the console. The created application will automatically display in myApplications, and you can take action on your applications.

When you choose your application in the Applications widget in the console, you can see an at-a-glance view of key application metrics widgets in the applications dashboard. Here you can find, debug operational issues, and optimize your applications.

With a single action on the applications dashboard, you can dive deeper to act on specific resources in the relevant services, such as Amazon CloudWatch for application performance, AWS Cost Explorer for cost and usage, and AWS Security Hub for security findings.

Getting started with myApplications
To get started, on the AWS Management Console Home, choose Create application in the Applications widget. In the first step, input your application name and description.

In the next step, you can add your resources. Before you can search and add resources, you should turn on and set up AWS Resource Explorer, a managed capability that simplifies the search and discovery of your AWS resources across AWS Regions.

Choose Add resources and select the resources to add to your applications. You can also search by keyword, tag, or AWS CloudFormation stack to integrate groups of resources to manage the full lifecycle of your application.

After confirming, your resources are added, new awsApplication tags applied, and the myApplications dashboard will be automatically generated.

Now, let’s see which widgets can be useful.

The Application summary widget displays the name, description, and tag so you know which application you are working on. The Cost and usage widget visualizes your AWS resource costs and usage from AWS Cost Explorer, including the application’s current and forecasted month-end costs, top five billed services, and a monthly application resource cost trend chart. You can monitor spend, look for anomalies, and click to take action where needed.

The Compute widget summarizes of application compute resources, information about which are in alarm, and trend charts from CloudWatch showing basic metrics such as Amazon EC2 instance CPU utilization and AWS Lambda invocations. You also can assess application operations, look for anomalies, and take action.

The Monitoring and Operations widget displays alarms and alerts for resources associated with your application, service level objectives (SLOs), and standardized application performance metrics from CloudWatch Application Signals. You can monitor ongoing issues, assess trends, and quickly identify and drill down on any issues that might impact your application.

The Security widget shows the highest priority security findings identified by AWS Security Hub. Findings are listed by severity and service, so you can monitor their security posture and click to take action where needed.

The DevOps widget summarizes operational insights from AWS System Manager Application Manager, such as fleet management, state management, patch management, and configuration management status so you can assess compliance and take action.

You can also use the Tagging widget to assist you in reviewing and applying tags to your application.

Now available
You can enjoy this new myApplications capability, a new application-centric experience to easily manage and monitor applications on AWS. myApplications capability is available in the following AWS Regions: US East (Ohio, N. Virginia), US West (N. California, Oregon), South America (São Paulo), Asia Pacific (Hyderabad, Jakarta, Mumbai, Osaka, Seoul, Singapore, Sydney, Tokyo), Europe (Frankfurt, Ireland, London, Paris, Stockholm), Middle East (Bahrain) Regions.

AWS Premier Tier Services Partners— Escala24x7, IBM, Tech Mahindra, and Xebia will support application operations with complementary features and services.

Give it a try now in the AWS Management Console and send feedback to AWS re:Post for AWS Management Console, using the feedback link on the myApplications dashboard, or through your usual AWS Support contacts.

— Channy

Package and deploy models faster with new tools and guided workflows in Amazon SageMaker

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/package-and-deploy-models-faster-with-new-tools-and-guided-workflows-in-amazon-sagemaker/

I’m happy to share that Amazon SageMaker now comes with an improved model deployment experience to help you deploy traditional machine learning (ML) models and foundation models (FMs) faster.

As a data scientist or ML practitioner, you can now use the new ModelBuilder class in the SageMaker Python SDK to package models, perform local inference to validate runtime errors, and deploy to SageMaker from your local IDE or SageMaker Studio notebooks.

In SageMaker Studio, new interactive model deployment workflows give you step-by-step guidance on which instance type to choose to find the most optimal endpoint configuration. SageMaker Studio also provides additional interfaces to add models, test inference, and enable auto scaling policies on the deployed endpoints.

New tools in SageMaker Python SDK
The SageMaker Python SDK has been updated with new tools, including ModelBuilder and SchemaBuilder classes that unify the experience of converting models into SageMaker deployable models across ML frameworks and model servers. Model builder automates the model deployment by selecting a compatible SageMaker container and capturing dependencies from your development environment. Schema builder helps to manage serialization and deserialization tasks of model inputs and outputs. You can use the tools to deploy the model in your local development environment to experiment with it, fix any runtime errors, and when ready, transition from local testing to deploy the model on SageMaker with a single line of code.

Amazon SageMaker ModelBuilder

Let me show you how this works. In the following example, I choose the Falcon-7B model from the Hugging Face model hub. I first deploy the model locally, run a sample inference, perform local benchmarking to find the optimal configuration, and finally deploy the model with the suggested configuration to SageMaker.

First, import the updated SageMaker Python SDK and define a sample model input and output that matches the prompt format for the selected model.

import sagemaker
from sagemaker.serve.builder.model_builder import ModelBuilder
from sagemaker.serve.builder.schema_builder import SchemaBuilder
from sagemaker.serve import Mode

prompt = "Falcons are"
response = "Falcons are small to medium-sized birds of prey related to hawks and eagles."

sample_input = {
    "inputs": prompt,
    "parameters": {"max_new_tokens": 32}
}

sample_output = [{"generated_text": response}]

Then, create a ModelBuilder instance with the Hugging Face model ID, a SchemaBuilder instance with the sample model input and output, define a local model path, and set the mode to LOCAL_CONTAINER to deploy the model locally. The schema builder generates the required functions for serializing and deserializing the model inputs and outputs.

model_builder = ModelBuilder(
    model="tiiuae/falcon-7b",
    schema_builder=SchemaBuilder(sample_input, sample_output),
    model_path="/path/to/falcon-7b",
    mode=Mode.LOCAL_CONTAINER,
	env_vars={"HF_TRUST_REMOTE_CODE": "True"}
)

Next, call build() to convert the PyTorch model into a SageMaker deployable model. The build function generates the required artifacts for the model server, including the inferency.py and serving.properties files.

local_mode_model = model_builder.build()

For FMs, such as Falcon, you can optionally run tune() in local container mode that performs local benchmarking to find the optimal model serving configuration. This includes the tensor parallel degree that specifies the number of GPUs to use if your environment has multiple GPUs available. Once ready, call deploy() to deploy the model in your local development environment.

tuned_model = local_mode_model.tune()
tuned_model.deploy()

Let’s test the model.

updated_sample_input = model_builder.schema_builder.sample_input
print(updated_sample_input)

{'inputs': 'Falcons are',
 'parameters': {'max_new_tokens': 32}}
 
local_tuned_predictor.predict(updated_sample_input)[0]["generated_text"]

In my demo, the model returns the following response:

a type of bird that are known for their sharp talons and powerful beaks. They are also known for their ability to fly at high speeds […]

When you’re ready to deploy the model on SageMaker, call deploy() again, set the mode to SAGEMAKLER_ENDPOINT, and provide an AWS Identity and Access Management (IAM) role with appropriate permissions.

sm_predictor = tuned_model.deploy(
    mode=Mode.SAGEMAKER_ENDPOINT, 
	role="arn:aws:iam::012345678910:role/role_name"
)

This starts deploying your model on a SageMaker endpoint. Once the endpoint is ready, you can run predictions.

new_input = {'inputs': 'Eagles are','parameters': {'max_new_tokens': 32}}
sm_predictor.predict(new_input)[0]["generated_text"])

New SageMaker Studio model deployment experience
You can start the new interactive model deployment workflows by selecting one or more models to deploy from the models landing page or SageMaker JumpStart model details page or by creating a new endpoint from the endpoints details page.

Amazon SageMaker - New Model Deployment Experience

The new workflows help you quickly deploy the selected model(s) with minimal inputs. If you used SageMaker Inference Recommender to benchmark your model, the dropdown will show instance recommendations from that benchmarking.

Model deployment experience in SageMaker Studio

Without benchmarking your model, the dropdown will display prospective instances that SageMaker predicts could be a good fit based on its own heuristics. For some of the most popular SageMaker JumpStart models, you’ll see an AWS pretested optimal instance type. For other models, you’ll see generally recommended instance types. For example, if I select the Falcon 40B Instruct model in SageMaker JumpStart, I can see the recommended instance types.

Model deployment experience in SageMaker Studio

Model deployment experience in SageMaker Studio

However, if I want to optimize the deployment for cost or performance to meet my specific use cases, I could open the Alternate configurations panel to view more options based on data from before benchmarking.

Model deployment experience in SageMaker Studio

Once deployed, you can test inference or manage auto scaling policies.

Model deployment experience in SageMaker Studio

Things to know
Here are a couple of important things to know:

Supported ML models and frameworks – At launch, the new SageMaker Python SDK tools support model deployment for XGBoost and PyTorch models. You can deploy FMs by specifying the Hugging Face model ID or SageMaker JumpStart model ID using the SageMaker LMI container or Hugging Face TGI-based container. You can also bring your own container (BYOC) or deploy models using the Triton model server in ONNX format.

Now available
The new set of tools is available today in all AWS Regions where Amazon SageMaker real-time inference is available. There is no cost to use the new set of tools; you pay only for any underlying SageMaker resources that get created.

Learn more

Get started
Explore the new SageMaker model deployment experience in the AWS Management Console today!

— Antje

Use natural language to explore and prepare data with a new capability of Amazon SageMaker Canvas

Post Syndicated from Irshad Buchh original https://aws.amazon.com/blogs/aws/use-natural-language-to-explore-and-prepare-data-with-a-new-capability-of-amazon-sagemaker-canvas/

Today, I’m happy to introduce the ability to use natural language instructions in Amazon SageMaker Canvas to explore, visualize, and transform data for machine learning (ML).

SageMaker Canvas now supports using foundation model- (FM) powered natural language instructions to complement its comprehensive data preparation capabilities for data exploration, analysis, visualization, and transformation. Using natural language instructions, you can now explore and transform your data to build highly accurate ML models. This new capability is powered by Amazon Bedrock.

Data is the foundation for effective machine learning, and transforming raw data to make it suitable for ML model building and generating predictions is key to better insights. Analyzing, transforming, and preparing data to build ML models is often the most time-consuming part of the ML workflow. With SageMaker Canvas, data preparation for ML is seamless and fast with 300+ built-in transforms, analyses, and an in-depth data quality insights report without writing any code. Starting today, the process of data exploration and preparation is faster and simpler in SageMaker Canvas using natural language instructions for exploring, visualizing, and transforming data.

Data preparation tasks are now accelerated through a natural language experience using queries and responses. You can quickly get started with contextual, guided prompts to understand and explore your data.

Say I want to build an ML model to predict house prices Using SageMaker Canvas. First, I need to prepare my housing dataset to build an accurate model. To get started with the new natural language instructions, I open the SageMaker Canvas application, and in the left navigation pane, I choose Data Wrangler. Under the Data tab and from the list of available datasets, I select the canvas-housing-sample.csv as the dataset, then select Create a data flow and choose Create. I see the tabular view of my dataset and an introduction to the new Chat for data prep capability.

data-flow

I select Chat for data prep, and it displays the chat interface with a set of guided prompts relevant to my dataset. I can use any of these prompts or query the data for something else.

chat-interface

First, I want to understand the quality of my dataset to identify any outliers or anomalies. I ask SageMaker Canvas to generate a data quality report to accomplish this task.

data-quality

I see there are no major issues with my data. I would now like to visualize the distribution of a couple of features in the data. I ask SageMaker Canvas to plot a chart.

query

I now want to filter certain rows to transform my data. I ask SageMaker Canvas to remove rows where the population is less than 1,000. Canvas removes those rows, shows me a preview of the transformed data, and also gives me the option to view and update the code that generated the transform.

code-view

I am happy with the preview and add the transformed data to my list of data transform steps on the right. SageMaker Canvas adds the step along with the code.

transform

Now that my data is transformed, I can go on to build my ML model to predict house prices and even deploy the model into production using the same visual interface of SageMaker Canvas, without writing a single line of code.

Data preparation has never been easier for ML!

Availability
The new capability in Amazon SageMaker Canvas to explore and transform data using natural language queries is available in all AWS Regions where Amazon SageMaker Canvas and Amazon Bedrock are supported.

Learn more
Amazon SageMaker Canvas product page

Go build!

— Irshad

Amazon SageMaker adds new inference capabilities to help reduce foundation model deployment costs and latency

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/amazon-sagemaker-adds-new-inference-capabilities-to-help-reduce-foundation-model-deployment-costs-and-latency/

Today, we are announcing new Amazon SageMaker inference capabilities that can help you optimize deployment costs and reduce latency. With the new inference capabilities, you can deploy one or more foundation models (FMs) on the same SageMaker endpoint and control how many accelerators and how much memory is reserved for each FM. This helps to improve resource utilization, reduce model deployment costs on average by 50 percent, and lets you scale endpoints together with your use cases.

For each FM, you can define separate scaling policies to adapt to model usage patterns while further optimizing infrastructure costs. In addition, SageMaker actively monitors the instances that are processing inference requests and intelligently routes requests based on which instances are available, helping to achieve on average 20 percent lower inference latency.

Key components
The new inference capabilities build upon SageMaker real-time inference endpoints. As before, you create the SageMaker endpoint with an endpoint configuration that defines the instance type and initial instance count for the endpoint. The model is configured in a new construct, an inference component. Here, you specify the number of accelerators and amount of memory you want to allocate to each copy of a model, together with the model artifacts, container image, and number of model copies to deploy.

Amazon SageMaker - MME

Let me show you how this works.

New inference capabilities in action
You can start using the new inference capabilities from SageMaker Studio, the SageMaker Python SDK, and the AWS SDKs and AWS Command Line Interface (AWS CLI). They are also supported by AWS CloudFormation.

For this demo, I use the AWS SDK for Python (Boto3) to deploy a copy of the Dolly v2 7B model and a copy of the FLAN-T5 XXL model from the Hugging Face model hub on a SageMaker real-time endpoint using the new inference capabilities.

Create a SageMaker endpoint configuration

import boto3
import sagemaker

role = sagemaker.get_execution_role()
sm_client = boto3.client(service_name="sagemaker")

sm_client.create_endpoint_config(
    EndpointConfigName=endpoint_config_name,
    ExecutionRoleArn=role,
    ProductionVariants=[{
        "VariantName": "AllTraffic",
        "InstanceType": "ml.g5.12xlarge",
        "InitialInstanceCount": 1,
		"RoutingConfig": {
            "RoutingStrategy": "LEAST_OUTSTANDING_REQUESTS"
        }
    }]
)

Create the SageMaker endpoint

sm_client.create_endpoint(
    EndpointName=endpoint_name,
    EndpointConfigName=endpoint_config_name,
)

Before you can create the inference component, you need to create a SageMaker-compatible model and specify a container image to use. For both models, I use the Hugging Face LLM Inference Container for Amazon SageMaker. These deep learning containers (DLCs) include the necessary components, libraries, and drivers to host large models on SageMaker.

Prepare the Dolly v2 model

from sagemaker.huggingface import get_huggingface_llm_image_uri

# Retrieve the container image URI
hf_inference_dlc = get_huggingface_llm_image_uri(
  "huggingface",
  version="0.9.3"
)

# Configure model container
dolly7b = {
    'Image': hf_inference_dlc,
    'Environment': {
        'HF_MODEL_ID':'databricks/dolly-v2-7b',
        'HF_TASK':'text-generation',
    }
}

# Create SageMaker Model
sagemaker_client.create_model(
    ModelName        = "dolly-v2-7b",
    ExecutionRoleArn = role,
    Containers       = [dolly7b]
)

Prepare the FLAN-T5 XXL model

# Configure model container
flant5xxlmodel = {
    'Image': hf_inference_dlc,
    'Environment': {
        'HF_MODEL_ID':'google/flan-t5-xxl',
        'HF_TASK':'text-generation',
    }
}

# Create SageMaker Model
sagemaker_client.create_model(
    ModelName        = "flan-t5-xxl",
    ExecutionRoleArn = role,
    Containers       = [flant5xxlmodel]
)

Now, you’re ready to create the inference component.

Create an inference component for each model
Specify an inference component for each model you want to deploy on the endpoint. Inference components let you specify the SageMaker-compatible model and the compute and memory resources you want to allocate. For CPU workloads, define the number of cores to allocate. For accelerator workloads, define the number of accelerators. RuntimeConfig defines the number of model copies you want to deploy.

# Inference compoonent for Dolly v2 7B
sm_client.create_inference_component(
    InferenceComponentName="IC-dolly-v2-7b",
    EndpointName=endpoint_name,
    VariantName=variant_name,
    Specification={
        "ModelName": "dolly-v2-7b",
        "ComputeResourceRequirements": {
		    "NumberOfAcceleratorDevicesRequired": 2, 
			"NumberOfCpuCoresRequired": 2, 
			"MinMemoryRequiredInMb": 1024
	    }
    },
    RuntimeConfig={"CopyCount": 1},
)

# Inference component for FLAN-T5 XXL
sm_client.create_inference_component(
    InferenceComponentName="IC-flan-t5-xxl",
    EndpointName=endpoint_name,
    VariantName=variant_name,
    Specification={
        "ModelName": "flan-t5-xxl",
        "ComputeResourceRequirements": {
		    "NumberOfAcceleratorDevicesRequired": 2, 
			"NumberOfCpuCoresRequired": 1, 
			"MinMemoryRequiredInMb": 1024
	    }
    },
    RuntimeConfig={"CopyCount": 1},
)

Once the inference components have successfully deployed, you can invoke the models.

Run inference
To invoke a model on the endpoint, specify the corresponding inference component.

import json
sm_runtime_client = boto3.client(service_name="sagemaker-runtime")
payload = {"inputs": "Why is California a great place to live?"}

response_dolly = sm_runtime_client.invoke_endpoint(
    EndpointName=endpoint_name,
    InferenceComponentName = "IC-dolly-v2-7b",
    ContentType="application/json",
    Accept="application/json",
    Body=json.dumps(payload),
)

response_flant5 = sm_runtime_client.invoke_endpoint(
    EndpointName=endpoint_name,
    InferenceComponentName = "IC-flan-t5-xxl",
    ContentType="application/json",
    Accept="application/json",
    Body=json.dumps(payload),
)

result_dolly = json.loads(response_dolly['Body'].read().decode())
result_flant5 = json.loads(response_flant5['Body'].read().decode())

Next, you can define separate scaling policies for each model by registering the scaling target and applying the scaling policy to the inference component. Check out the SageMaker Developer Guide for detailed instructions.

The new inference capabilities provide per-model CloudWatch metrics and CloudWatch Logs and can be used with any SageMaker-compatible container image across SageMaker CPU- and GPU-based compute instances. Given support by the container image, you can also use response streaming.

Now available
The new Amazon SageMaker inference capabilities are available today in AWS Regions US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Jakarta, Mumbai, Seoul, Singapore, Sydney, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, London, Stockholm), Middle East (UAE), and South America (São Paulo). For pricing details, visit Amazon SageMaker Pricing. To learn more, visit Amazon SageMaker.

Get started
Log in to the AWS Management Console and deploy your FMs using the new SageMaker inference capabilities today!

— Antje

Introducing highly durable Amazon OpenSearch Service clusters with 30% price/performance improvement

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/introducing-highly-durable-amazon-opensearch-service-clusters-with-30-price-performance-improvement/

You can use the new OR1 instances to create Amazon OpenSearch Service clusters that use Amazon Simple Storage Service (Amazon S3) for primary storage. You can ingest, store, index, and access just about any imaginable amount of data, while also enjoying a 30% price/performance improvement over existing instance types, eleven nines of data durability, and a zero-time Recovery Point Objective (RPO). You can use this to perform interactive log analytics, monitor application in real time, and more.

New OR1 Instances
These benefits are all made possible by the new OR1 instances, which are available in eight sizes and used for the data nodes of the cluster:

Instance Name vCPUs
Memory
EBS Storage Max (gp3)
or1.medium.search 1 8 GiB 400 GiB
or1.large.search 2 16 GiB 800 GiB
or1.xlarge.search 4 32 GiB 1.5 TiB
or1.2xlarge.search 8 64 GiB 3 TiB
or1.4xlarge.search 16 128 GiB 6 TiB
or1.8xlarge.search 32 256 GiB 12 TiB
or1.12xlarge.search 48 384 GiB 18 TiB
or1.16xlarge.search 64 512 GiB 24 TiB

To choose a suitable instance size, read Sizing Amazon OpenSearch Service domains.

The Amazon Elastic Block Store (Amazon EBS) volumes are used for primary storage, with data copied synchronously to S3 as it arrives. The data in S3 is used to create replicas and to rehydrate EBS after shards are moved between instances as a result of a node failure or a routine rebalancing operation. This is made possible by the remote-backed storage and segment replication features that were recently released for OpenSearch.

Creating a Domain
To create a domain I open the Amazon OpenSearch Service Console, select Managed clusters, and click Create domain:

I enter a name for my domain (my-domain), select Standard create, and use the Production template:

Then I choose the Domain with standby deployment option. This option will create active data nodes in two Availability Zones and a standby one in a third. I also choose the latest engine version:

Then I select the OR1 instance family and (for my use case) configure 500 GiB of EBS storage per data node:

I set the other settings as needed, and click Create to proceed:

I take a quick lunch break and when i come back my domain is ready:

Things to Know
Here are a couple of things to know about this new storage option:

Engine Versions – Amazon OpenSearch Service engines version 2.11 and above support OR1 instances.

Regions – The OR1 instance family is available for use with OpenSearch in the US East (Ohio, N. Virginia), US West (N. California, Oregon), Asia Pacific (Mumbai, Singapore, Sydney, Tokyo), and Europe (Frankfurt, Ireland, Spain, Stockholm) AWS Regions.

Pricing – You pay On-Demand or Reserved prices for data nodes, and you also pay for EBS storage. See the Amazon OpenSearch Service Pricing page for more information.

— Jeff;

Evaluate, compare, and select the best foundation models for your use case in Amazon Bedrock (preview)

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/evaluate-compare-and-select-the-best-foundation-models-for-your-use-case-in-amazon-bedrock-preview/

I’m happy to share that you can now evaluate, compare, and select the best foundation models (FMs) for your use case in Amazon Bedrock. Model Evaluation on Amazon Bedrock is available today in preview.

Amazon Bedrock offers a choice of automatic evaluation and human evaluation. You can use automatic evaluation with predefined metrics such as accuracy, robustness, and toxicity. For subjective or custom metrics, such as friendliness, style, and alignment to brand voice, you can set up human evaluation workflows with just a few clicks.

Model evaluations are critical at all stages of development. As a developer, you now have evaluation tools available for building generative artificial intelligence (AI) applications. You can start by experimenting with different models in the playground environment. To iterate faster, add automatic evaluations of the models. Then, when you prepare for an initial launch or limited release, you can incorporate human reviews to help ensure quality.

Let me give you a quick tour of Model Evaluation on Amazon Bedrock.

Automatic model evaluation
With automatic model evaluation, you can bring your own data or use built-in, curated datasets and pre-defined metrics for specific tasks such as content summarization, question and answering, text classification, and text generation. This takes away the heavy lifting of designing and running your own model evaluation benchmarks.

To get started, navigate to the Amazon Bedrock console, then select Model evaluation under Assessment & deployment in the left menu. Create a new model evaluation and choose Automatic.

Amazon Bedrock Model Evaluation

Next, follow the setup dialog to choose the FM you want to evaluate and the type of task, for example, text summarization. Select the evaluation metrics and specify a dataset—either built-in or your own.

If you bring your own dataset, make sure it’s in JSON Lines format, and each line contains all of the key-value pairs that you want to evaluate your model with for the model dimension that you want to evaluate. For example, if you want to evaluate the model on a question-answer task, you would format your data as follows (with category being optional):

{"referenceResponse":"Cantal","category":"Capitals","prompt":"Aurillac is the capital of"}
{"referenceResponse":"Bamiyan Province","category":"Capitals","prompt":"Bamiyan city is the capital of"}
{"referenceResponse":"Abkhazia","category":"Capitals","prompt":"Sokhumi is the capital of"}
...

Then, create and run the evaluation job to understand the model’s task-specific performance. Once the evaluation job is complete, you can review the results in the model evaluation report.

Amazon Bedrock Model Evaluations

Human model evaluation
For human evaluation, you can have Amazon Bedrock set up human review workflows with a few clicks. You can bring your own datasets and define custom evaluation metrics, such as relevance, style, or alignment to brand voice. You also have the choice to either leverage your own internal teams as reviewers or engage an AWS managed team. This takes away the tedious effort of building and operating human evaluation workflows.

To get started, create a new model evaluation and select Human: Bring your own team or Human: AWS managed team.

If you choose an AWS managed team for human evaluation, describe your model evaluation needs, including task type, expertise of the work team, and the approximate number of prompts, along with your contact information. In the next step, an AWS expert will reach out to discuss your model evaluation project requirements in more detail. Upon review, the team will share a custom quote and project timeline.

If you choose to bring your own team, follow the setup dialog to choose the FMs you want to evaluate and the type of task, for example, text summarization. Then, select the evaluation metrics, upload your test dataset, and set up the work team.

For human evaluation, you would format the example data shown before again in JSON Lines format like this (with category and referenceResponse being optional):

{"prompt":"Aurillac is the capital of","referenceResponse":"Cantal","category":"Capitals"}
{"prompt":"Bamiyan city is the capital of","referenceResponse":"Bamiyan Province","category":"Capitals"}
{"prompt":"Senftenberg is the capital of","referenceResponse":"Oberspreewald-Lausitz","category":"Capitals"}

Once the human evaluation is completed, Amazon Bedrock generates an evaluation report with the model’s performance against your selected metrics.

Amazon Bedrock Model Evaluation

Things to know
Here are a couple of important things to know:

Model support – During preview, you can evaluate and compare text-based large language models (LLMs) available on Amazon Bedrock. During preview, you can select one model for each automatic evaluation job and up to two models for each human evaluation job using your own team. For human evaluation using an AWS managed team, you can specify custom project requirements.

Pricing – During preview, AWS only charges for the model inference needed to perform the evaluation (processed input and output tokens for on-demand pricing). There will be no separate charges for human evaluation or automatic evaluation. Amazon Bedrock Pricing has all the details.

Join the preview
Automatic evaluation and human evaluation using your own work team are available today in public preview in AWS Regions US East (N. Virginia) and US West (Oregon). Human evaluation using an AWS managed team is available in public preview in AWS Region US East (N. Virginia). To learn more, visit the Amazon Bedrock Developer Experience web page and check out the User Guide.

Get started
Log in to the AWS Management Console and start exploring model evaluation in Amazon Bedrock today!

— Antje

Amazon Redshift adds new AI capabilities, including Amazon Q, to boost efficiency and productivity

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-redshift-adds-new-ai-capabilities-to-boost-efficiency-and-productivity/

Amazon Redshift puts artificial intelligence (AI) at your service to optimize efficiencies and make you more productive with two new capabilities that we are launching in preview today.

First, Amazon Redshift Serverless becomes smarter. It scales capacity proactively and automatically along dimensions such as the complexity of your queries, their frequency, the size of the dataset, and so on to deliver tailored performance optimizations. This allows you to spend less time tuning your data warehouse instances and more time getting value from your data.

Second, Amazon Q generative SQL in Amazon Redshift Query Editor generates SQL recommendations from natural language prompts. This helps you to be more productive in extracting insights from your data.

Let’s start with Amazon Redshift Serverless
When you use Amazon Redshift Serverless, you can now opt in for a preview of AI-driven scaling and optimizations. When enabled, the system observes and learns from your usage patterns, such as the concurrent number of queries, their complexity, and the time it takes to run them. Then, it automatically optimizes your serverless endpoint to meet your price performance target. Based on AWS internal testing, this new capability may give you up to ten times better price performance for variable workloads without any manual intervention.

AI-driven scaling and optimizations eliminate the time and effort to manually resize your workgroup and plan background optimizations based on workload needs. It continually runs automatic optimizations when they are most valuable for better performance, avoiding performance cliffs and time-outs.

This new capability goes beyond the existing self-tuning capabilities of Amazon Redshift Serverless, such as machine learning (ML)-enhanced techniques to adjust your compute, modify the physical schema of the database, create or drop materialized views as needed (the one we manage automatically, not yours), and vacuum tables. This new capability brings more intelligence to decide how to adjust the compute, what background optimizations are required, and when to apply them, and it makes its decisions based on more dimensions. We also orchestrate ML-based optimizations for materialized views, table optimizations, and workload management when your queries need it.

During the preview, you must opt in to enable these AI-driven scaling and optimizations on your workgroups. You configure the system to balance the optimization for price or performance. There is only one slider to adjust in the console.

Redshift serverless - AI driven workgoups

As usual, you can track resource usage and associated changes through the console, Amazon CloudWatch metrics, and the system table SYS_SERVERLESS_USAGE.

Now, let’s look at Amazon Q generative SQL in Amazon Redshift Query Editor
What if you could use generative AI to help analysts write effective SQL queries more rapidly? This is the new experience we introduce today in Amazon Redshift Query Editor, our web-based SQL editor.

You can now describe the information you want to extract from your data in natural language, and we generate the SQL query recommendations for you. Behind the scenes, Amazon Q generative SQL uses a large language model (LLM) and Amazon Bedrock to generate the SQL query. We use different techniques, such as prompt engineering and Retrieval Augmented Generation (RAG), to query the model based on your context: the database you’re connected to, the schema you’re working on, your query history, and optionally the query history of other users connected to the same endpoint. The system also remembers previous questions. You can ask it to refine a previously generated query.

The SQL generation model uses metadata specific to your data schema to generate relevant queries. For example, it uses the table and column names and the relationship between the tables in your database. In addition, your database administrator can authorize the model to use the query history of all users in your AWS account to generate even more relevant SQL statements. We don’t share your query history with other AWS accounts and we don’t train our generation models with any data coming from your AWS account. We maintain the high level of privacy and security that you expect from us.

Using generated SQL queries helps you to get started when discovering new schemas. It does the heavy lifting of discovering the column names and relationships between tables for you. Senior analysts also benefit from asking what they want in natural language and having the SQL statement automatically generated. They can review the queries and run them directly from their notebook.

Let’s explore a schema and extract information
For this demo, let’s pretend I am a data analyst at a company that sells concert tickets. The database schema and data are available for you to download. My manager asks me to analyze the ticket sales data to send a thank you note with discount coupons to the highest-spending customers in Seattle.

I connect to Amazon Redshift Query Editor and connect the analytic endpoint. I create a new tab for a Notebook (SQL generation is available from notebooks only).

Instead of writing a SQL statement, I open the chat panel and type, “Find the top five users from Seattle who bought the most number of tickets in 2022.” I take the time to verify the generated SQL statement. It seems correct, so I decide to run it. I select Add to notebook and then Run. The query returns the list of the top five buyers in Seattle.

sql generation - top 5 users

I had no previous knowledge of the data schema, and I did not type a single line of SQL to find the information I needed.

But generative SQL is not limited to a single interaction. I can chat with it to dynamically refine the queries. Here is another example.

I ask “Which state has the most venues?” Generative SQL proposes the following query. The answer is New York, with 49 venues, if you’re curious.

generative sql chat 01

I changed my mind, and I want to know the top three cities with the most venues. I simply rephrase my question: “What about the top three venues?”

generative sql chat 02

I add the query to the notebook and run it. It returns the expected result.

generative sql chat 03

Best practices for prompting
Here are a couple of tips and tricks to get the best results out of your prompts.

Be specific – When asking questions in natural language, be as specific as possible to help the system understand exactly what you need. For example, instead of writing “find the top venues that sold the most tickets,” provide more details like “find the names of the top three venues that sold the most tickets in 2022.” Use consistent entity names like venue, ticket, and location instead of referring to the same entity in different ways, which can confuse the system.

Iterate – Break your complex requests into multiple simple statements that are easier for the system to interpret. Iteratively ask follow-up questions to get more detailed analysis from the system. For example, start by asking, “Which state has the most venues?” Then, based on the response, ask a follow-up question like “Which is the most popular venue from this state?”

Verify – Review the generated SQL before running it to ensure accuracy. If the generated SQL query has errors or does not match your intent, provide instructions to the system on how to correct it instead of rephrasing the entire request. For example, if the query is missing a filter clause on year, write “provide venues from year 2022.”

Availability and pricing
AI-driven scaling and optimizations are in preview in six AWS Regions: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Tokyo), and Europe (Ireland, Stockholm). They come at no additional cost. You pay only for the compute capacity your data warehouse consumes when it is active. Pricing is per Redshift Processing Unit (RPU) per hour. The billing is per second of used capacity. The pricing page for Amazon Redshift has the details.

Amazon Q generative SQL for Amazon Redshift Query Editor is in preview in two AWS Regions today: US East (N. Virginia) and US West (Oregon). There is no charge during the preview period.

These are two examples of how AI helps to optimize performance and increase your productivity, either by automatically adjusting the price-performance ratio of your Amazon Redshift Serverless endpoints or by generating correct SQL statements from natural language prompts.

Previews are essential for us to capture your feedback before we make these capabilities available for all. Experiment with these today and let us know what you think on the re:Post forums or using the feedback button on the bottom left side of the console.

— seb

AWS Clean Rooms Differential Privacy enhances privacy protection of your users data (preview)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-clean-rooms-differential-privacy-enhances-privacy-protection-of-your-users-data-preview/

Starting today, you can use AWS Clean Rooms Differential Privacy (preview) to help protect the privacy of your users with mathematically backed and intuitive controls in a few steps. As a fully managed capability of AWS Clean Rooms, no prior differential privacy experience is needed to help you prevent the reidentification of your users.

AWS Clean Rooms Differential Privacy obfuscates the contribution of any individual’s data in generating aggregate insights in collaborations so that you can run a broad range of SQL queries to generate insights about advertising campaigns, investment decisions, clinical research, and more.

Quick overview on differential privacy
Differential privacy is not new. It is a strong, mathematical definition of privacy compatible with statistical and machine learning based analysis, and has been used by the United States Census Bureau as well as companies with vast amounts of data.

Differential privacy helps with a wide variety of use cases involving large datasets, where adding or removing a few individuals has a small impact on the overall result, such as population analyses using count queries, histograms, benchmarking, A/B testing, and machine learning.

The following illustration shows how differential privacy works when it is applied to SQL queries.

When an analyst runs a query, differential privacy adds a carefully calibrated amount of error (also referred to as noise) to query results at run-time, masking the contribution of individuals while still keeping the query results accurate enough to provide meaningful insights. The noise is carefully fine-tuned to mask the presence or absence of any possible individual in the dataset.

Differential privacy also has another component called privacy budget. The privacy budget is a finite resource consumed each time a query is run and thus controls the number of queries that can be run on your datasets, helping ensure that the noise cannot be averaged out to reveal any private information about an individual. When the privacy budget is fully exhausted, no more queries can be run on your tables until it is increased or refreshed.

However, differential privacy is not easy to implement because this technique requires an in-depth understanding of mathematically rigorous formulas and theories to apply it effectively. Configuring differential privacy is also a complex task because customers need to calculate the right level of noise in order to preserve the privacy of their users without negatively impacting the utility of query results.

Customers also want to enable their partners to conduct a wide variety of analyses including highly complex and customized queries on their data. This requirement is hard to support with differential privacy because of the intricate nature of the calculations involved in calibrating the noise while processing various query components such as aggregations, joins, and transformations.

We created AWS Clean Rooms Differential Privacy to help you protect the privacy of your users with mathematically backed controls in a few clicks.

How differential privacy works in AWS Clean Rooms
While differential privacy is quite a sophisticated technique, AWS Clean Rooms Differential Privacy makes it easy for you to apply it and protect the privacy of your users with mathematically backed, flexible, and intuitive controls. You can begin using it with just a few steps after starting or joining an AWS Clean Rooms collaboration as a member with abilities to contribute data.

You create a configured table, which is a reference to your table in the AWS Glue Data Catalog, and choose to turn on differential privacy while adding a custom analysis rule to the configured table.

Next, you associate the configured table to your AWS Clean Rooms collaboration and configure a differential privacy policy in the collaboration to make your table available for querying. You can use a default policy to quickly complete the setup or customize it to meet your specific requirements. As part of this step, you will configure the following:

Privacy budget
Quantified as a value that we call epsilon, the privacy budget controls the level of privacy protection. It is a common, finite resource that is applied for all of your tables protected with differential privacy in the collaboration because the goal is to preserve the privacy of your users whose information can be present in multiple tables. The privacy budget is consumed every time a query is run on your tables. You have the flexibility to increase the privacy budget value any time during the collaboration and automatically refresh it each calendar month.

Noise added per query
Measured in terms of the number of users whose contributions you want to obscure, this input parameter governs the rate at which the privacy budget is depleted.

In general, you need to balance your privacy needs against the number of queries you want to permit and the accuracy of those queries. AWS Clean Rooms makes it easy for you to complete this step by helping you understand the resulting utility you are providing to your collaboration partner. You can also use the interactive examples to understand how your chosen settings would impact the results for different types of SQL queries.

Now that you have successfully enabled differential privacy protection for your data, let’s see AWS Clean Rooms Differential Privacy in action. For this demo, let’s assume I am your partner in the AWS Clean Rooms collaboration.

Here, I’m running a query to count the number of overlapping customers and the result shows there are 3,227,643 values for tv.customer_id.

Now, if I run the same query again after removing records about an individual from coffee_customers table, it shows a different result, 3,227,604 tv.customer_id. This variability in the query results prevents me from identifying the individuals from observing the difference in query results.

I can also see the impact of differential privacy, including the remaining queries I can run.

Available for preview
Join this preview and start protecting the privacy of your users with AWS Clean Rooms Differential Privacy. During this preview period, you can use AWS Clean Rooms Differential Privacy wherever AWS Clean Rooms is available. To learn more on how to get started, visit the AWS Clean Rooms Differential Privacy page.

Happy collaborating!
— Donnie

AWS Clean Rooms ML helps customers and partners apply ML models without sharing raw data (preview)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-clean-rooms-ml-helps-customers-and-partners-apply-ml-models-without-sharing-raw-data-preview/

Today, we’re introducing AWS Clean Rooms ML (preview), a new capability of AWS Clean Rooms that helps you and your partners apply machine learning (ML) models on your collective data without copying or sharing raw data with each other. With this new capability, you can generate predictive insights using ML models while continuing to protect your sensitive data.

During this preview, AWS Clean Rooms ML introduces its first model specialized to help companies create lookalike segments for marketing use cases. With AWS Clean Rooms ML lookalike, you can train your own custom model, and you can invite partners to bring a small sample of their records to collaborate and generate an expanded set of similar records while protecting everyone’s underlying data.

In the coming months, AWS Clean Rooms ML will release a healthcare model. This will be the first of many models that AWS Clean Rooms ML will support next year.

AWS Clean Rooms ML helps you to unlock various opportunities for you to generate insights. For example:

  • Airlines can take signals about loyal customers, collaborate with online booking services, and offer promotions to users with similar characteristics.
  • Auto lenders and car insurers can identify prospective auto insurance customers who share characteristics with a set of existing lease owners.
  • Brands and publishers can model lookalike segments of in-market customers and deliver highly relevant advertising experiences.
  • Research institutions and hospital networks can find candidates similar to existing clinical trial participants to accelerate clinical studies (coming soon).

AWS Clean Rooms ML lookalike modeling helps you apply an AWS managed, ready-to-use model that is trained in each collaboration to generate lookalike datasets in a few clicks, saving months of development work to build, train, tune, and deploy your own model.

How to use AWS Clean Rooms ML to generate predictive insights
Today I will show you how to use lookalike modeling in AWS Clean Rooms ML and assume you have already set up a data collaboration with your partner. If you want to learn how to do that, check out the AWS Clean Rooms Now Generally Available — Collaborate with Your Partners without Sharing Raw Data post.

With your collective data in the AWS Clean Rooms collaboration, you can work with your partners to apply ML lookalike modeling to generate a lookalike segment. It works by taking a small sample of representative records from your data, creating a machine learning (ML) model, then applying the particular model to identify an expanded set of similar records from your business partner’s data.

The following screenshot shows the overall workflow for using AWS Clean Rooms ML.

By using AWS Clean Rooms ML, you don’t need to build complex and time-consuming ML models on your own. AWS Clean Rooms ML trains a custom, private ML model, which saves months of your time while still protecting your data.

Eliminating the need to share data
As ML models are natively built within the service, AWS Clean Rooms ML helps you protect your dataset and customer’s information because you don’t need to share your data to build your ML model.

You can specify the training dataset using the AWS Glue Data Catalog table, which contains user-item interactions.

Under Additional columns to train, you can define numerical and categorical data. This is useful if you need to add more features to your dataset, such as the number of seconds spent watching a video, the topic of an article, or the product category of an e-commerce item.

Applying custom-trained AWS-built models
Once you have defined your training dataset, you can now create a lookalike model. A lookalike model is a machine learning model used to find similar profiles in your partner’s dataset without either party having to share their underlying data with each other.

When creating a lookalike model, you need to specify the training dataset. From a single training dataset, you can create many lookalike models. You also have the flexibility to define the date window in your training dataset using Relative range or Absolute range. This is useful when you have data that is constantly updated within AWS Glue, such as articles read by users.

Easy-to-tune ML models
After you create a lookalike model, you need to configure it to use in AWS Clean Rooms collaboration. AWS Clean Rooms ML provides flexible controls that enable you and your partners to tune the results of the applied ML model to garner predictive insights.

On the Configure lookalike model page, you can choose which Lookalike model you want to use and define the Minimum matching seed size you need. This seed size defines the minimum number of profiles in your seed data that overlap with profiles in the training data.

You also have the flexibility to choose whether the partner in your collaboration receives metrics in Metrics to share with other members.

With your lookalike models properly configured, you can now make the ML models available for your partners by associating the configured lookalike model with a collaboration.

Creating lookalike segments
Once the lookalike models have been associated, your partners can now start generating insights by selecting Create lookalike segment and choosing the associated lookalike model for your collaboration.

Here on the Create lookalike segment page, your partners need to provide the Seed profiles. Examples of seed profiles include your top customers or all customers who purchased a specific product. The resulting lookalike segment will contain profiles from the training data that are most similar to the profiles from the seed.

Lastly, your partner will get the Relevance metrics as the result of the lookalike segment using the ML models. At this stage, you can use the Score to make a decision.

Export data and use programmatic API
You also have the option to export the lookalike segment data. Once it’s exported, the data is available in JSON format and you can process this output by integrating with AWS Clean Rooms API and your applications.

Join the preview
AWS Clean Rooms ML is now in preview and available via AWS Clean Rooms in US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Seoul, Singapore, Sydney, Tokyo), and Europe (Frankfurt, Ireland, London). Support for additional models is in the works.

Learn how to apply machine learning with your partners without sharing underlying data on the AWS Clean Rooms ML page.

Happy collaborating!
— Donnie