Threat Actors Using AWS WorkMail in Phishing Campaigns

Post Syndicated from Jan Blažek original https://www.rapid7.com/blog/post/dr-threat-actors-aws-workmail-phishing-campaigns

Introduction

At Rapid7, we track a wide range of threats targeting cloud environments, where a frequent objective is hijacking victim infrastructure to host phishing or spam campaigns. Beyond the obvious security risks, this approach allows threat actors to offload their operational costs onto the target company, often resulting in significant, unwanted bills for services the victim never intended to use.

Rapid7 recently investigated a cloud abuse incident in which threat actors leveraged compromised AWS credentials to deploy phishing and spam infrastructure using AWS WorkMail, bypassing the anti-abuse controls normally enforced by AWS Simple Email Service (SES). AWS SES is a general-purpose, API-driven email platform intended for application-generated email such as transactional notifications and marketing messages. This allows the threat actor to leverage Amazon’s high sender reputation to masquerade as a valid business entity, with the ability to send email directly from victim-owned AWS infrastructure. Generating minimal service-attributed telemetry also makes threat actor activity difficult to distinguish from routine activity. Any organization with exposed AWS credentials and permissive Identity and Access Management (IAM) policies are potentially at risk, particularly those without guardrails or monitoring around WorkMail and SES configuration.

In this post, we analyzed a real-world incident observed by our MDR team in which threat actors abused native AWS email services to build phishing and spam infrastructure inside a compromised cloud environment. We will reconstruct the attacker’s progression from credential validation and IAM reconnaissance to bypassing Amazon SES safeguards by pivoting to AWS WorkMail. Along the way, we highlight how legitimate service abstractions can be leveraged to evade detection, examine the resulting logging and attribution gaps, and outline practical detection and prevention strategies defenders can use to identify and disrupt similar cloud-native abuse.

Background: AWS WorkMail and its key components

AWS WorkMail is a fully managed business email and calendaring service that allows organizations to operate corporate mailboxes without deploying or maintaining their own mail servers. It supports standard email protocols such as IMAP and SMTP, as well as common desktop and mobile clients, making it a lightweight, pay-as-you-go alternative for teams already operating within AWS.

To understand the activities performed by threat actors in the incident, it’s important to first introduce several core concepts within AWS WorkMail.

Organization

An Organization is the top-level container in WorkMail. It represents an isolated email environment that holds all users, groups, and domains. Each WorkMail organization is region-specific and operates independently, which allows attackers to create disposable, self-contained email infrastructures with minimal setup.

Users

Users represent individual mail-enabled identities within a WorkMail organization. After a user is created using the “workmail:CreateUser” API call, a mailbox can be assigned via a “workmail:RegisterToWorkMail”API call. Once registered, the user can authenticate to the AWS WorkMail web client or connect via standard email protocols and immediately begin sending and receiving email.

Groups

Groups are collections of users that can receive email on behalf of multiple members. They are typically used for distribution lists or shared inboxes and can simplify bulk message delivery or internal coordination within a WorkMail organization.

Domains

Domains define the email address namespace used by a WorkMail organization ([email protected]). Before a domain can be used, ownership must be verified. This verification process leverages the standard domain verification mechanism of Amazon Simple Email Service, typically via DNS records. Once verified, the domain can be actively used for sending and receiving email, enabling threat actors to operate from attacker-controlled, but seemingly legitimate, domains.

Attack analysis

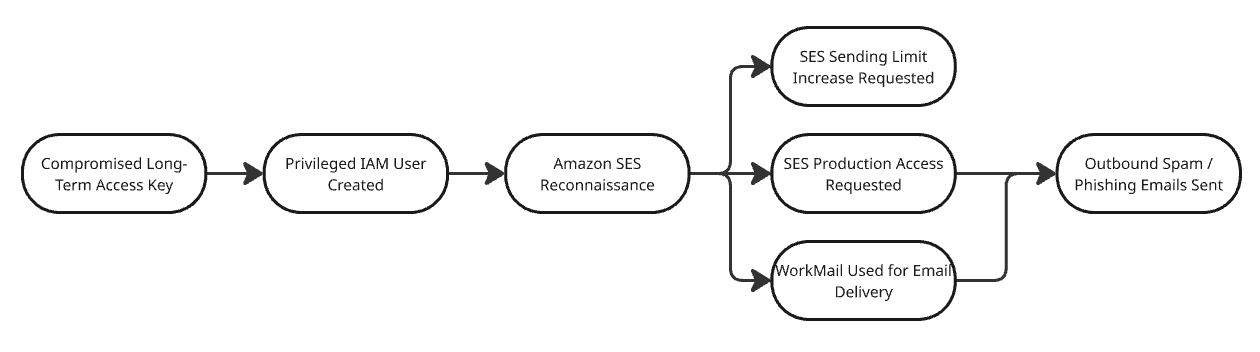
The diagram below contains a graphical representation of the key events carried out by the attackers throughout the attack, starting with initial access actions, continuing through privilege escalation, and ending with the achievement of objectives.
Graphical-visualization-of-AWS-workmail-phishing-attack.png
Figure 1: Graphical visualization of the attack

Initial access

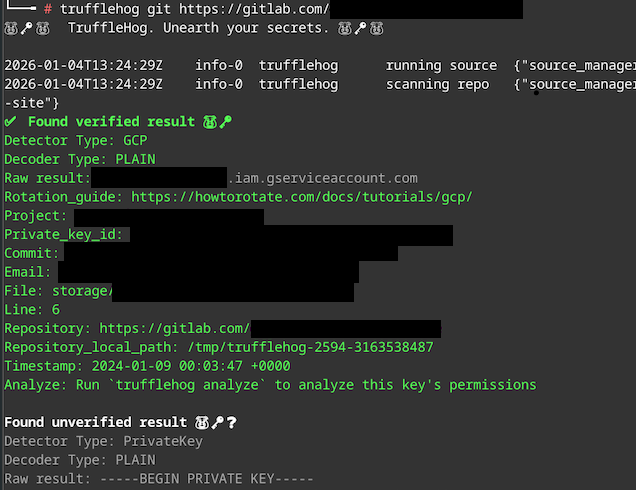
The compromise began with the exposure of long-term AWS access keys. The first indication of malicious activity was an “sts:GetCallerIdentity” API call with the User-Agent set to “TruffleHog Firefox.” This strongly suggests the use of TruffleHog, a tool commonly leveraged by adversaries to discover and validate leaked credentials from sources such as GitHub, GitLab, and public S3 buckets. Rapid7 has frequently observed TruffleHog usage in active campaigns, including activity attributed to groups such as the Crimson Collective.

Several days after this initial credential validation, we observed suspicious activity involving a second IAM user authenticated via long-term access keys. While we cannot conclusively prove that both users were accessed by the same operator, multiple factors suggest they were part of the same intrusion activity. Notably, both authentications originated from the same geographic region, which was anomalous for the victim’s normal operating patterns. Throughout the incident window, access to both accounts was conducted through a rotating set of IP addresses associated primarily with cloud service providers such as Amazon and DigitalOcean. This infrastructure choice is consistent with common adversary tradecraft used to obfuscate true origin and blend into legitimate cloud-to-cloud traffic.

⠀
TruffleHog-output-discovered-credentials-for-Google-Cloud-Platform.png
Figure 2: Example TruffleHog output showing discovered credentials for Google Cloud Platform (GCP)

Discovery phase and privilege escalation

Following initial access, the first compromised user was used to perform basic environment discovery via native AWS APIs. These attempts repeatedly resulted in AccessDenied errors, indicating that the exposed credentials were constrained by limited permissions. The activity was conducted using the AWS command-line interface (CLI), suggesting hands-on, interactive exploration by the threat actor rather than automated tooling.

After encountering these limitations, the adversary shifted activity to the second set of compromised credentials, which possessed significantly broader permissions. With this user, enumeration became more deliberate and structured. The actor began with iam:ListUsers API calls to understand the identity landscape and then used a technique of intentionally triggering API errors to confirm specific permissions without making persistent changes.

As part of this broader discovery effort, the actor also queried Amazon SES to assess its current configuration and readiness for abuse. Specifically, they executed ses:GetAccount and ses:ListIdentities. These calls allowed the adversary to quickly map the operational status of SES within the account. The ses:ListIdentities API call was used to determine whether any verified identities (domains or email addresses) already existed that could be immediately leveraged for sending mail; none were present at the time. In parallel, ses:GetAccount was used to identify whether the account was operating in the SES sandbox, which would impose strict sending limits and require additional steps before large-scale email campaigns could be launched.

This SES-focused reconnaissance indicates early intent to abuse email-sending capabilities and demonstrates how attackers can efficiently evaluate service readiness using only a small number of low-noise management API calls.

For example, the actor attempted to create an IAM user that already existed. The resulting error response confirmed possession of iam:CreateUser permissions without successfully creating a new entity:

⠀

{
"userAgent": "aws-cli/1.22.34 Python/3.10.12 Linux/5.15.0-113-generic botocore/1.23.34",
"errorCode": "EntityAlreadyExistsException",
"errorMessage": "User with name xxxx already exists."
}

Listing 1: Part of the iam:CreateUser CloudTrail log

⠀

A similar validation was performed using iam:CreateLoginProfile. By supplying a password that violated the account’s password policy, the actor received a PasswordPolicyViolationException, confirming their ability to create console login profiles:

⠀

{
"userAgent": "aws-cli/1.22.34 Python/3.10.12 Linux/5.15.0-113-generic botocore/1.23.34",
"errorCode": "PasswordPolicyViolationException",
"errorMessage": "Password should have at least one uppercase letter"
}

Listing 2: Part of the iam:CreateLoginProfile CloudTrail log

⠀

After validating the scope of their privileges, the adversary created a new IAM user, attached the AWS managed policy “AdministratorAccess”, and established a login profile to enable AWS Management Console access. This marked a transition from CLI-based reconnaissance to full GUI-based control, providing unrestricted access and setting the stage for subsequent operational activity.

Action on objectives: Preparing email infrastructure for abuse

By the end of the discovery phase, the threat actor had established two critical facts:

  1. No verified identities existed in Amazon Simple Email Service (SES).

  2. The account remained restricted by the SES sandbox.

The SES sandbox is explicitly designed to limit fraud and abuse, and its restrictions effectively prevent meaningful phishing or spam campaigns. While an account remains in the sandbox, the following controls apply:

  • Emails can only be sent to verified identities (email addresses or domains) or the SES mailbox simulator.

  • A maximum of 200 messages per 24-hour period.

  • A maximum sending rate of 1 message per second.

These constraints made SES unsuitable for immediate abuse at scale. Rather than abandoning the service, the attacker initiated a process to legitimize higher-volume email sending.

First, they opened a support case with AWS requesting removal from the SES sandbox. In parallel, they requested a substantial increase to the daily sending quota— setting it to 100,000 emails per day —using the servicequotas:RequestServiceQuotaIncrease API call.

⠀

{
    "requestParameters": {
"serviceCode": "ses",
"quotaCode": "L-XXXXXX",
"desiredValue": 100000
	
}

Listing 3: Request parameters from RequestServiceQuotaIncrease API call

⠀

During this waiting period, the actor focused on persistence and stealth. Multiple IAM users were created.. These usernames were deliberately chosen to resemble region- or service-scoped automation accounts rather than human operators. To further reduce suspicion during IAM audits, the attacker attached narrowly scoped, SES-only policies to these users instead of broad administrative permissions. This approach allowed them to preserve operational access while minimizing obvious indicators of compromise such as over-privileged identities.

At this stage, the attacker had effectively prepared the account for large-scale email abuse-but they did not wait for AWS approval to proceed.

Bypassing SES controls by abusing AWS WorkMail

Rather than remaining idle while SES sandbox removal and quota increases were pending, the attacker pivoted to AWS WorkMail, which offers an alternative email-sending pathway with significantly fewer upfront restrictions.

Using the workmail:CreateOrganization API, the threat actor created multiple WorkMail organizations. They then initiated domain verification workflows for domains designed to appear legitimate and business-like, including:

  • cloth-prelove[.]me

  • ipad-service-london[.]com

Domain verification was performed through ses:VerifyDomainIdentity and ses:VerifyDomainDkim, with the calls originating from workmail.amazonaws.com. This highlights an important nuance for defenders: although SES APIs are involved, the activity is driven by WorkMail provisioning rather than traditional SES email campaigns.

Once domain verification was completed, the actor created multiple mailbox users directly within WorkMail, such as:

  • service@ipad-service-london[.]com

  • marketing@ipad-service-london[.]com

These accounts served two purposes. First, they established persistence at the application layer, independent of IAM. Second, they provided credible sender identities for phishing and spam operations, closely resembling legitimate corporate email addresses.

There were also AWS directory service events logged by CloudTrail that show new aliases created for the new sender domains, using the victim’s directory tenant:

CreateAlias

AuthorizeAppication

This pivot is particularly impactful because AWS WorkMail does not implement a sandbox model comparable to SES. Emails can be sent immediately to external, unverified recipients. Additionally, WorkMail supports significantly higher sending volumes than SES sandbox limits. While Rapid7 has not empirically validated the maximum throughput, AWS documentation cites a default upper limit of 100,000 external recipients per day per organization, aggregated across all users.

Email sending methods and logging gaps

The attacker had two viable options for sending email through WorkMail:

1. Web interface
Emails sent through the AWS WorkMail web client may surface indirectly in CloudTrail as “ses:SendRawEmail” events. These events are generated because WorkMail uses Amazon Simple Email Service (SES) as its underlying mail transport, even though the messages are composed and sent entirely through the WorkMail application.

While these events are not attributed to an IAM principal, they do expose several pieces of valuable metadata within the “requestParameters” field — most notably the sender’s email address and associated SES identity. This allows defenders to link outbound email activity to specific WorkMail users and recently verified domains, even in the absence of traditional application or message-level logs.

One notable limitation of these “ses:SendRawEmail” events is the absence of a true client source IP address. Because emails sent via the WorkMail web interface are executed by an AWS-managed service on behalf of the mailbox user, CloudTrail records the “sourceIPAddress” as “workmail.<region>.amazonaws.com” rather than the originating IP address of the actor’s browser session. This effectively obscures the attacker’s true network origin and prevents defenders from correlating email-sending activity with suspicious IP ranges, TOR exit nodes, or previously observed intrusion infrastructure.

⠀

{
"eventVersion": "1.11",
"userIdentity": {
"type": "AWSService",
"invokedBy": "workmail.us-east-1.amazonaws.com"
    },
"eventTime": "2025-12-20T11:26:59Z",
"eventSource": "ses.amazonaws.com",
"eventName": "SendRawEmail",
"awsRegion": "us-east-1",
"sourceIPAddress": "workmail.us-east-1.amazonaws.com",
"userAgent": "workmail.us-east-1.amazonaws.com",
"requestParameters": {
"sourceArn": "arn:aws:ses:us-east-1:123456789012:identity/malicious-organiation[.]com",
"destinations": [
"HIDDEN_DUE_TO_SECURITY_REASONS"
        ],
"source": "=?UTF-8?Q?Malicious_User?= <marketing@malicious-organiation[.]com>",
"fromArn": "arn:aws:ses:us-east-1:123456789012:identity/malicious-organiation[.]com",
"configurationSetName": "gcp-iad-prod-workmail-default-configuration-set",
"rawMessage": {
"data": "HIDDEN_DUE_TO_SECURITY_REASONS"
        }
    },
"responseElements": null,
"additionalEventData": {
"SignatureVersion": "4",
"sesMessageId": "0100019b3c4a8bb7-50af951c-fbd4-4610-bc94-c7fc35733699-000000"
    },
"requestID": "aff61405-04bd-4969-802a-7ce4d5946949",
"eventID": "c34ed12d-5bec-3fdd-aef9-57ae4313ca88",
"readOnly": true,
"resources": [
        {
"accountId": "123456789012",
"type": "AWS::SES::ConfigurationSet",
"ARN": "arn:aws:ses:us-east-1:123456789012:configuration-set/gcp-iad-prod-workmail-default-configuration-set"
        },
        {
"accountId": "123456789012",
"type": "AWS::SES::EmailIdentity",
"ARN": "arn:aws:ses:us-east-1:123456789012:identity/malicious-organiation[.]com"
        }
    ],
"eventType": "AwsApiCall",
"managementEvent": false,
"recipientAccountId": "123456789012",
"sharedEventID": "xxx",
"eventCategory": "xxx"}

Listing 4: SendRawEmail event logged after an email is sent via AWS WorkMail web interface⠀

⠀

While limited, this telemetry can still be valuable for correlating suspicious sending behavior with recently created WorkMail users or newly verified domains.

2. SMTP access
Alternatively, the attacker can authenticate directly to WorkMail’s SMTP endpoint and send messages programmatically. Emails sent via SMTP do not generate CloudTrail events, even when SES data events are enabled, creating a significant blind spot for defenders.

An example Python script used to send email through WorkMail SMTP is shown below:

⠀

import smtplib
from email.message import EmailMessage

# Configuration
SMTP_SERVER = "smtp.mail.us-east-1.awsapps.com"
SMTP_PORT = 465
EMAIL_ADDRESS = "[email protected]"
EMAIL_PASSWORD = "****"

# Create the message
msg = EmailMessage()
msg["Subject"] = "WorkMail SMTP"
msg["From"] = EMAIL_ADDRESS
msg["To"] = "<unverified_email>"
msg.set_content("Email Delivered to an Unverified Email via AWS WorkMail")

# Send the email
try:
with smtplib.SMTP_SSL(SMTP_SERVER, SMTP_PORT) as smtp:
smtp.login(EMAIL_ADDRESS, EMAIL_PASSWORD)
smtp.send_message(msg)
print("Email sent successfully!")
except Exception as e:
print(f"Error: {e}")

Listing 5: Example script sending messages via AWS WorkMail via SMTP

⠀

From an attacker’s perspective, this method is ideal: higher volume, immediate external reach, and minimal centralized logging. From a defender’s perspective, it underscores the importance of monitoring WorkMail organization creation, domain verification events, and mailbox provisioning, as these actions often precede phishing activity that will never be visible in CloudTrail.

Conclusion

This incident illustrates how threat actors can abuse higher-level AWS services to deploy phishing and spam infrastructure closely resembling legitimate enterprise usage. While AWS WorkMail is not designed to support bulk email operations, attackers can still leverage it as an interim capability alongside Amazon SES. By abusing WorkMail’s authenticated mailboxes and relaxed upfront controls, adversaries can begin sending lower volumes of email immediately — well before SES is moved out of the sandbox and higher sending quotas are approved. This staged approach allows attackers to establish sender reputation, validate infrastructure, and maintain operational momentum while bypassing many of the friction points intentionally built into SES.

To mitigate this class of abuse, organizations should combine preventive guardrails with focused detection. Where AWS WorkMail is not required, its use should be explicitly blocked using AWS Organizations Service Control Policies (SCPs) to prevent organization creation and mailbox provisioning. In environments where WorkMail is needed, IAM policies should enforce strict least-privilege access and treat WorkMail and SES administration as privileged operations subject to monitoring and approval. Finally, organizations should reduce the likelihood of initial access by implementing secure development and operational practices — such as secret scanning in code repositories, regular key rotation, and minimizing long-term access keys — to limit the impact of credential leakage and prevent attackers from converting compromised credentials into scalable email abuse.

MITRE ATT&CK techniques

Tactic

Technique

Details

Initial Access

Valid Accounts: Cloud Accounts (T1078.004)

The attacker authenticated to AWS using exposed long-term access keys validated with sts:GetCallerIdentity

Persistence

Create Account: Cloud Account (T1136.003)

The attacker created multiple IAM users and AWS WorkMail mailbox users to maintain persistent access

Privilege Escalation

Account Manipulation: Additional Cloud Roles (T1098.003)

The attacker attached the AdministratorAccess managed policy to a newly created IAM user

Discovery

Cloud Infrastructure Discovery (T1580)

The attacker enumerated IAM users and assessed Amazon SES configuration and sandbox status via API calls

Impact

Resource Hijacking: Cloud Service Hijacking (T1496.004)

The attacker abused AWS WorkMail and SES to send high-volume phishing and spam emails from the victim account

Indicators of compromise (IOCs)

139.59.117[.]125

3.0.205[.]202

54.151.176[.]0

Note: IP addresses 3.0.205[.]202 and 54.151.176[.]0 are Amazon owned IP addresses so care should be taken when applying IP blocks.

Rapid7 customers

InsightIDR and Managed Detection and Response (MDR) customers have existing detection coverage through Rapid7’s expansive library of detection rules. These detections are deployed and will alert on the behaviors described in this technical analysis.

A critical GnuPG security update

Post Syndicated from corbet original https://lwn.net/Articles/1056209/

There is a new GnuPG update for a “critical security bug” in recent
GnuPG releases.

A crafted CMS (S/MIME) EnvelopedData message carrying an oversized
wrapped session key can cause a stack buffer overflow in gpg-agent
during the PKDECRYPT–kem=CMS handling. This can easily be used
for a DoS but, worse, the memory corruption can very likley also be
used to mount a remote code execution attack. The bug was
introduced while changing an internal API to the FIPS required KEM
API.

Only versions 2.5.13 through 2.5.16 are affected.

The GNU C Library is moving from Sourceware

Post Syndicated from corbet original https://lwn.net/Articles/1056206/

GNU C Library maintainer Carlos O’Donell has announced
that the project will be moving its core services away from Sourceware in favor of services hosted
at the Linux Foundation.

While it was clear to the GNU Toolchain leadership that
requirements were coming to improve the toolchain cyber-security
posture, these requirements were not clear to all project
developers. As part of receiving this feedback we have worked to
document and define a secure development policy for glibc and at a
higher level the GNU Toolchain. While Sourceware has started
making some critical technical changes, the GNU Toolchain still
faces serious, systemic concerns about securing a global, highly
available service and building a sustainable, diverse sponsorship
model.

This has been a long-running discussion; see this 2022 article for some background.

[$] Implicit arguments for BPF kfuncs

Post Syndicated from corbet original https://lwn.net/Articles/1055559/

The kernel’s “kfunc” mechanism is a way of exporting kernel functions so
that they can be called directly from BPF programs. There are over 300
kfuncs in current kernels, ranging in functionality from string processing
(bpf_strnlen())
to custom schedulers (scx_bpf_kick_cpu())
and beyond. Sometimes these kfuncs need access to context information that
is not directly available to BPF programs, and which thus cannot be passed
in as arguments. The implicit
arguments patch set
from Ihor Solodrai is the latest attempt to solve
this problem.

Decoding Zabbix Proxy Traffic for Faster Troubleshooting

Post Syndicated from Kaspars Mednis original https://blog.zabbix.com/decoding-zabbix-proxy-traffic-for-faster-troubleshooting/31898/

Usually, it is enough to simply look at the Zabbix proxy administration page or proxy health metrics to perform basic proxy troubleshooting. However, there are situations when a deeper look is required.

Today, we will examine the Zabbix server ↔ proxy communication and learn how to interpret the internal communication protocol.

Understanding the protocol

Zabbix communication protocol

Zabbix components use TCP for communication, and information is encoded in JSON. How do you distinguish Zabbix communication packets? There are a few main filters you need to apply:

  • Protocol: TCP

  • Port: 10051 or 10050 (depending on whether components are active or passive)

  • Packet: Starts with ZBXD or 5A 42 58 44 in HEX

On older versions, it was simple to capture and read Zabbix packets in plain text. Starting with Zabbix 4.0.0, mandatory traffic compression was implemented. This greatly reduces network traffic – roughly by 10× with negligible CPU overhead, but it also makes the traffic unreadable to humans.

A modern Zabbix communication packet looks like this:

5a425844038200000097000000789c2dcccb0e83201085e15731b33606b90a8fe20ec631256da4056a6c9abe7be965fb7f27e709996e772a151c5c733a1edde2ab871e4ee9db661f423cba1f79ac71a786854a89696bbe7223e5b2326b75e01c199368510b42cf68f2eaf3b453fe8fcdc0063eb68497846770a3d1c25a698cea612be0b43642a9c9b2d71b6c5d2cfd

Not very human-friendly, right? In the following sections we will capture and decompress this communication packet step by step.

Capturing traffic

There are multiple tools available for this purpose, but we will use Wireshark – one of the most popular and widely used packet analysis tools. It provides a nice graphical interface for Windows and Linux, but we will use the command-line version, since most troubleshooting is performed over an SSH session. The system used in this example is CentOS Stream 9, but the commands should work on other Linux distributions with only minor syntax adjustments.

First, install the tool:

dnf install wireshark-cli

This installs the tshark command-line utility. After that, change your working directory to a location where you can write files. In this example, we will use /tmp:

cd /tmp

Next, let’s capture some traffic between the Zabbix server and an active proxy:

tshark -i eth0 -f "host <ZABBIX SERVER IP> and host <ZABBIX PROXY IP> \
and tcp port 10051" -w zabbix_stream.pcap

Explanation of parameters:

  • -i eth0 – listen on interface eth0 (specify a different interface if needed)

  • <ZABBIX SERVER IP> – replace with the Zabbix server IP address

  • <ZABBIX PROXY IP> – replace with the Zabbix proxy IP address

  • tcp port 10051 – capture TCP packets on port 10051 (Zabbix trapper)

  • -w zabbix_stream.pcap – write captured output to a file

Let this run for a couple of minutes to collect some raw traffic data. Press CTRL + C to stop the capture.

Analyzing capture file

Now we have captured a *.pcap file that contains multiple TCP streams. A TCP stream represents a single TCP connection. Since Zabbix proxies do not keep persistent connections and instead open a new connection whenever needed, a Zabbix active proxy typically produces the following streams:

  • Data sender – sends collected values every second (by default)

  • Configuration syncer – downloads configuration updates every 10 seconds (by default)

To view the contents of the *.pcap file, run:

tshark -r zabbix_stream.pcap -q -z conv,tcp

Example output:

TCP Conversations
Filter:<No Filter>
                                   |      <-    ||      ->    ||     Total   |Relative|
                                   |Frames Bytes||Frames Bytes||Frames Bytes |Start   |       
10.10.0.2:57850 <-> 10.20.0.5:10051 5 2,512bytes  6 547bytes    11 3,059bytes 0.0000   
10.10.0.2:57860 <-> 10.20.0.5:10051 5 399bytes    5 516bytes    10 915bytes   0.4700  
10.10.0.2:57864 <-> 10.20.0.5:10051 5 399bytes    5 521bytes    10 920bytes   1.4768  
10.10.0.2:57876 <-> 10.20.0.5:10051 5 399bytes    5 570bytes    10 969bytes   2.4829   
10.10.0.2:57878 <-> 10.20.0.5:10051 5 399bytes    5 522bytes    10 921bytes   3.4882   
10.10.0.2:46628 <-> 10.20.0.5:10051 5 399bytes    5 527bytes    10 926bytes   4.4935   
10.10.0.2:46642 <-> 10.20.0.5:10051 4 333bytes    6 590bytes    10 923bytes   5.4992   
10.10.0.2:46648 <-> 10.20.0.5:10051 5 399bytes    5 478bytes    10 877bytes   6.5047   
10.10.0.2:46662 <-> 10.20.0.5:10051 5 399bytes    5 480bytes    10 879bytes   7.5097
We can print packets in chronological order, including stream numbers:
tshark -r zabbix_stream.pcap -T fields \
-e tcp.stream -e frame.number -e frame.time_relative -e frame.len
Column meaning in example output:
  1. Stream number

  2. Frame number

  3. Relative timestamp from the start of capture

  4. Frame size in bytes

0 1  0.000000000 76
0 2  0.000005109 76
0 3  0.000078403 68
0 4  0.000079579 68
0 5  0.000280946 209
0 6  0.000283835 209
0 7  0.001188322 68
0 8  0.001189912 68
0 9  0.001421210 68
0 10 0.001422856 68
1 11 1.003582601 76
1 12 1.003588266 76
1 13 1.003646494 68
1 14 1.003647585 68
1 15 1.003741654 256
1 16 1.003758183 256
1 17 1.004531106 68
1 18 1.004532827 68
1 19 1.004973531 68
.....

To include the payload (Zabbix communication), add the -e tcp.payload field:

tshark -r zabbix_stream.pcap -T fields \
-e tcp.stream -e frame.number -e frame.time_relative -e frame.len -e tcp.payload

Example (truncated for readability):

0 1  0.000000000 76
0 2  0.000005109 76
0 3  0.000078403 68
0 4  0.000079579 68
0 5  0.000280946 209 5a425844038000000096000000789c2dca4d0e82301040e1ab90591352fb3703477137d3d6483454692518e3dd6dd4edfbde0bd6747fa4526182db9af76717b932f470cedf76649179ef7ec4a1ce5b6a585229735e9a2bf12aa2481c89299032c2ceb21754a44fda609bb7b4fe671cece05a09d71c2e301dd05b4548daf4b014984667b52734f6fd013eac2c96
0 6  0.000283835 209 5a425844038000000096000000789c2dca4d0e82301040e1ab90591352fb3703477137d3d6483454692518e3dd6dd4edfbde0bd6747fa4526182db9af76717b932f470cedf76649179ef7ec4a1ce5b6a585229735e9a2bf12aa2481c89299032c2ceb21754a44fda609bb7b4fe671cece05a09d71c2e301dd05b4548daf4b014984667b52734f6fd013eac2c96
0 7  0.001188322 68
0 8  0.001189912 68
0 9  0.001421210 68
0 10 0.001422856 68
......

Not all frames contain payload — the empty ones represent TCP handshakes and other control packets. We are interested only in frames containing payload, because this is where Zabbix data lives.

Analyzing payload

If you take a closer look, each payload starts with a sequence of 5a 42 58 44 – or “ZBXD” in ASCII. This is the Zabbix packet signature and confirms that we have captured the correct traffic.

Example:

5a42584403af000000f0000000789c658ecb0e823014447f85dc3521853e6edb4fd1b868a1c646b44a0bc110fedd22ec5cce9ce4cc2c30b8f7e862020daf21cc9fa233c94009b7f0eb4ec65a3f173b326df293cb30ba187d78664eac201d5adb2969642b09b58633232c12d95c1b8a9bc9c7148643accf0bf80e34150d2bc127f7d812278cd312da3eb477d0350a4624ca2657cf081a15e74cd588254ca61f5d9ead61bde4e486e30656ace2f06f60bb417154825056af5fed34456b
The full Zabbix header is the first 13 bytes of each packet: 5a 42 58 44 03 af 00 00 00 f0 00 00 00 
  • 5a 42 58 44 – Zabbix packet signature ZBXD

  • 03 – Flags (0x01 Zabbix protocol + 0x02 compression)

  • af 00 00 00 – Data length

  • f0 00 00 00 – Length of uncompressed data

The next header is: 78 9c  which indicates zlib compression. After this comes the compressed JSON data we are interested in. More information can be found within Zabbix documentation here.

Let’s extract only the payload with command:

tshark -r zabbix_stream.pcap -T fields -e tcp.payload -E occurrence=f \
| grep -v '^$'
  • -T fields: output only selected fields

  • -e tcp.payload: get the payload of each TCP frame

  • -E occurrence=f: include all occurrences per frame

  • grep -v ‘^$’: remove empty lines (frames with no payload)

Output example:

5a425844038000000096000000789c2dca4d0e82301040e1ab90591352fb3703477137d3d6483454692518e3dd6dd4edfbde0bd6747fa4526182db9af76717b932f470cedf76649179ef7ec4a1ce5b6a585229735e9a2bf12aa2481c89299032c2ceb21754a44fda609bb7b4fe671cece05a09d71c2e301dd05b4548daf4b014984667b52734f6fd013eac2c96                                                                                5a425844038000000096000000789c2dca4d0e82301040e1ab90591352fb3703477137d3d6483454692518e3dd6dd4edfbde0bd6747fa4526182db9af76717b932f470cedf76649179ef7ec4a1ce5b6a585229735e9a2bf12aa2481c89299032c2ceb21754a44fda609bb7b4fe671cece05a09d71c2e301dd05b4548daf4b014984667b52734f6fd013eac2c96                                                                                5a42584403af000000f0000000789c658ecb0e823014447f85dc3521853e6edb4fd1b868a1c646b44a0bc110fedd22ec5cce9ce4cc2c30b8f7e862020daf21cc9fa233c94009b7f0eb4ec65a3f173b326df293cb30ba187d78664eac201d5adb2969642b09b58633232c12d95c1b8a9bc9c7148643a

Decompressing payload

First, let’s save the payload to a file:

tshark -r zabbix_stream.pcap -T fields -e tcp.payload -E occurrence=f \
| grep -v '^$'  > zabbix_payload.hex

Next, create a python script named decompress.py.

#!/usr/bin/python3
import zlib

hex_file = "zabbix_payload.hex"
ZBXD_HEADER_LEN = 26 # 13 bytes * 2 hex chars per byte

with open(hex_file, "r") as f:
  for line_number, line in enumerate(f, 1):
    line = line.strip()
    if not line:
      continue

    # Remove Zabbix header
    if line.startswith("5a425844"):
      payload_hex = line[ZBXD_HEADER_LEN:]
    else:
      payload_hex = line

    # Convert hex to bytes
    try:
      payload_bytes = bytes.fromhex(payload_hex)
    except ValueError as e:
      print(f"Line {line_number}: Invalid hex, skipping ({e})")
      continue

    # Decompress using zlib
    try:
      decompressed = zlib.decompress(payload_bytes)
    except zlib.error as e:
      print(f"Line {line_number}: Decompression error ({e})")
      continue
  
    print(f"Line {line_number}: {decompressed}")

Make the file executable:

chmod +x decompress.py

Execute the file:

./decompress.py

The script will output decompressed Zabbix traffic:

Line 59: b'{"request":"proxy data","host":"Zabbix proxy active","session":"fbdb545d8250bb4c9b2341cc8ca055f1","history data":[{"id":13,"itemid":50454,"clock":1764172374,"ns":946257883,"value":"[{\\"{#IFNAME}\\":\\"lo\\"},{\\"{#IFNAME}\\":\\"eth0\\"}]"}],"version":"7.4.5","clock":1764172375,"ns":432069960}'
Line 60: b'{"upload":"enabled","response":"success","tasks":[{"type":6,"clock":1764172373,"ttl":3600,"itemid":50454}]}'
Line 61: b'{"request":"proxy data","host":"Zabbix proxy active","session":"fbdb545d8250bb4c9b2341cc8ca055f1","version":"7.4.5","clock":1764172375,"ns":438122213}'
Line 62: b'{"upload":"enabled","response":"success"}'
Line 63: b'{"request":"proxy config","host":"Zabbix proxy active","version":"7.4.5","session":"fbdb545d8250bb4c9b2341cc8ca055f1", "config_revision":18611,"proxy_secrets_provider":0}'
Line 64: b'{"data":{},"config_revision":18613}'

Here every line represents a request from a Zabbix active proxy or Zabbix server response. It is easy to distinguish two communication types:

  • Request proxy data – Proxy sends collected values
  • Request proxy config – Proxy checks its configuration revision and downloads configuration changes if required
Recap

It is required to run only three commands in this setup to read uncompressed communications:

tshark -i eth0 -f "host <ZABBIX SERVER IP> and host <ZABBIX PROXY IP> \
and tcp port 10051" -w zabbix_stream.pcap

tshark -r zabbix_stream.pcap -T fields -e tcp.payload -E occurrence=f \
| grep -v '^$' > zabbix_payload.hex

./decompress.py

A more human-readable format

Can we improve it? Absolutely! Let’s pair requests with their corresponding responses for easier parsing, and then output the data as formatted JSON. First, capture the data:

tshark -i eth0 -f "host <ZABBIX SERVER IP> and host <ZABBIX PROXY IP> \
and tcp port 10051" -w zabbix_stream.pcap

Next, extract the data into a CSV while keeping the stream number:

tshark -r zabbix_stream.pcap -T fields -e tcp.stream -e tcp.payload \
-E occurrence=f -E separator=, -E quote=d, -Y 'tcp.payload && tcp.payload != ""' \
> zabbix_payload.csv

Now, the CSV contains both the stream number and the payload for each packet.

"2","5a42584403aa000000dd000000789c458d410e83201444af62fe9a1814a896a3b4e9e283df9494480bd4688c772f694dba9d37336f8348af37a50c1a9e312c6b35604660700fdfec82c6b8a5fa21b4d9cd5460a2945c980a1fcd60945443df2a6e8cb467d30ad958db5be44a8d4d29bb29531cd15285333a8fc6799757d0d7ed8fdc005a080647c31368ce80620cb14860bf3198291eceae96b52ac7d607fb00dd7427d974ad506531a5f2c3c599ab9ecbfd038a0944ee" "2","5a425844033000000029000000789cab562a2dc8c94f4c51b2524acd4b4cca494d51d2512a4a2d2ec8cf2b4e050a16972627a716172bd502002b010e61" "3","5a42584403db0000003d010000789c658fdd6ac3300c855f25e8da143bb6f2e317196cecc23f0a33f3e2cd76434be9bbcf4d03bbd89584bea3a3a31b64fa3953a9a0e13ba7cbb5f3a61a60f091f6d9abb1365cba2732ae868d1a2c544a486be38bf51615faa9476ead72b3eda512ce4dce70c4453471582be5c538eacc66423436c450afa0df6e7f2878d05232381491400b069473caed08dcdf5ba0506aca47be7dd9efa250e9ebd12257c819b898dc6703e3a0c4d8cbc7682da06735e1340e02196c269e9b3fbc90ed0ae58df2eedfeaf1d378522784ff56e2692545afe6990fc3fd17684060c8" "3","5a425844033000000029000000789cab562a2dc8c94f4c51b2524acd4b4cca494d51d2512a4a2d2ec8cf2b4e050a16972627a716172bd502002b010e61"

Next, let’s create a slightly modified Python script to display the entries per stream. Name it streams.py:

#!/usr/bin/python3

import csv
import zlib
import json

csv_file = "zabbix_payload.csv"
ZBXD_HEADER_LEN = 26 # 13 bytes * 2 hex chars per byte
streams = {}
with open(csv_file, "r") as f:
  reader = csv.reader(f)
  for row_number, row in enumerate(reader, 1):
    if len(row) < 2:
       continue

    stream_id = row[0].strip().strip('"')
    hexdata = row[1].strip().strip('"')

    if not hexdata:
      continue

    # Remove Zabbix header
    if hexdata.startswith("5a425844"):
      hex_payload = hexdata[ZBXD_HEADER_LEN:]
    else:
      hex_payload = hexdata

    # Convert hex to bytes
    try:
      payload_bytes = bytes.fromhex(hex_payload)
    except ValueError as e:
      print(f"[Line {row_number}] Invalid hex: {e}")
      continue

    # Decompress
    try:
      decompressed = zlib.decompress(payload_bytes)
    except zlib.error as e:
      print(f"[Line {row_number}] Decompression error: {e}")
      continue

    # Store in the stream bucket
    streams.setdefault(stream_id, []).append(decompressed)

# ---- OUTPUT SECTION ----

print("\n===== STREAM PAIRS =====\n")

for stream_id, messages in streams.items():
  print(f"=== Stream {stream_id} ===")
  for i, msg in enumerate(messages):
    label = (
      "Request:" if i == 0
      else "Response:" if i == 1
      else f"Extra message #{i+1}:"
    )
    print(label)
    text = msg.decode("utf-8")

    # Try to pretty-print JSON
    try:
      parsed = json.loads(text)
      pretty_json = json.dumps(parsed, indent=4, ensure_ascii=False)
      print(pretty_json)
    except json.JSONDecodeError:
    # fallback: print raw text
      print(text)
    print()

Make the file executable:

chmod +x streams.py

Execute the file:

./streams.py

The script will output decompressed Zabbix traffic in a parsed JSON format:

=== Stream 0 ===
Request:
{
  "request": "proxy data",
  "host": "Zabbix proxy active",
  "session": "fbdb545d8250bb4c9b2341cc8ca055f1",
  "interface availability": [
    {
      "interfaceid": 33,
      "available": 0,
      "error": ""
    }
  ],
  "version": "7.4.5",
  "clock": 1764172350,
  "ns": 303905804
}
Response:
{
  "upload": "enabled",
  "response": "success"
}

=== Stream 1 ===
Request:
.......

You’ll notice that typical communication produces two entries per stream – one request from the Zabbix proxy and one response from the Zabbix server. With this approach, it’s much easier to understand and troubleshoot the communication – all traffic is now grouped into request-response pairs and presented in a clean, formatted way.

Live data

And finally — can we make all of this run live? Absolutely, with a little help from our third Python script. The previous two examples walked through the workflow step by step: capture → extract payload → decompress. Now everything comes together in a single script that handles the entire process for you.

Create a new file named live.py:

#!/usr/bin/python3

import subprocess
import zlib
import json
from datetime import datetime

ZBXD_HEADER_LEN = 26 # 13 bytes * 2 hex chars

# === Configurable parameters ===
SRC_IP = "161.35.217.186"
DST_IP = "134.209.233.72"
TCP_PORT = "10051"
INTERFACE = "eth0"

tshark_cmd = [
  "tshark",
  "-i", INTERFACE,
  "-l",
  "-f", f"host {SRC_IP} and host {DST_IP} and tcp port {TCP_PORT}",
  "-T", "fields",
  "-e", "tcp.stream",
  "-e", "tcp.payload",
  "-E", "separator=,",
  "-E", "quote=d",
  "-E", "occurrence=f",
  "-Y", "tcp.payload && tcp.payload != \"\""
]

proc = subprocess.Popen(
  tshark_cmd,
  stdout=subprocess.PIPE,
  stderr=subprocess.DEVNULL,
  text=True
)

seen_streams = set() # track streams we've already printed

for line in proc.stdout:
  line = line.strip()
  if not line:
    continue

  # Split CSV (stream_number, payload_hex)
  try:
    stream_num, payload_hex = line.split(",", 1)
    payload_hex = payload_hex.strip('"')
  except ValueError:
    continue

  # Only print timestamp once per stream
  if stream_num not in seen_streams:
    timestamp = datetime.now().strftime("%Y-%m-%d %H:%M:%S.%f")[:-3]
    print(f"\n=== [{timestamp}] Stream {stream_num} ===")
    seen_streams.add(stream_num)

  # Remove Zabbix header
  if payload_hex.startswith("5a425844"):
    payload_hex = payload_hex[ZBXD_HEADER_LEN:]

  # Convert hex to bytes
  try:
    payload_bytes = bytes.fromhex(payload_hex)
  except ValueError:
    continue

  # Decompress
  try:
    decompressed = zlib.decompress(payload_bytes)
  except zlib.error:
    continue

  # Pretty print JSON if possible
  try:
    json_obj = json.loads(decompressed)
    pretty = json.dumps(json_obj, indent=2)
    print(pretty)
  except json.JSONDecodeError:
    print(decompressed)

Make the file executable:

chmod +x live.py

Execute the file:

./live.py

And that’s it – your script now watches live proxy traffic and streams the output as JSON. Pretty cool, right?

=== [2025-11-27 16:59:31.593] Stream "0" ===
{
  "request": "proxy data",
  "host": "Zabbix proxy active",
  "session": "fbdb545d8250bb4c9b2341cc8ca055f1",
  "history data": [
    {
      "id": 73726,
      "itemid": 50459,
      "clock": 1764262769,
      "ns": 947018320,
      "value": "0"
    },
    {
      "id": 73727,
      "itemid": 50450,
      "clock": 1764262770,
      "ns": 947145177
    }
  ],
  "version": "7.4.5",
  "clock": 1764262770,
  "ns": 961735298
}
{
  "upload": "enabled",
"  response": "success"
}
.....

Final notes

The example scripts provided here are for demonstration purposes only, tested in a small demo environment. While the same principles apply to larger setups, keep in mind that proxies in production can handle hundreds or even thousands of new values per second (NVPS), which significantly increases the payload volume. Also, all examples assume a Zabbix proxy running in active mode – passive proxies communicate slightly differently. A similar approach can be used to monitor Zabbix Agent communications.

So, what valuable information can you actually gather from Zabbix proxy ⇄ Zabbix Server communication?

  • The types of data sent from proxy to server

  • Configuration updates and their contents

  • Test and Execute Now tasks

  • Discovery and Autoregistration data

If you’re interested in exploring discovery, autoregistration, encryption, or other aspects of Zabbix’s internal communication, feel free to leave a comment!

The post Decoding Zabbix Proxy Traffic for Faster Troubleshooting appeared first on Zabbix Blog.

Xfwl4: the roadmap for a Xfce Wayland compositor

Post Syndicated from jzb original https://lwn.net/Articles/1056159/

The Xfce team has announced that
it will be providing funding to Brian Tarricone to work on xfwl4,
a Wayland compositor for Xfce:

Xfwl4 will not be based on the existing xfwm4 code. Instead, it
will be written from scratch in rust, using smithay building
blocks.

The first attempt at creating an Xfce Wayland compositor involved
modifying the existing xfwm4 code to support both X11 and Wayland in
parallel. However, this approach turned out to be the wrong path
forward for several reasons:

  • Xfwm4 is architected in a way that makes it very difficult to put the window management behavior behind generic interfaces that don’t include X11 specifics.
  • Refactoring Xfwm4 is risky, since it might introduce new bugs to X11. Having two parallel code bases will allow for rapid development and experimentation with the Wayland compositor, with zero risk to break xfwm4.
  • Some X11 window management concepts just aren’t available or supported by Wayland protocols at this time, and dealing with those differences can be difficult in an X11-first code base.
  • Using the existing codebase would require us to use C and
    wlroots, even if a better alternative is available.

Work has already commenced on the project, and the project hopes to
share a development release in mid-2026.

The End of the Road for Cisco Kenna: Take a Measured Path into Exposure Management

Post Syndicated from Michael Chroney original https://www.rapid7.com/blog/post/em-eol-cisco-kenna-new-measured-path-into-exposure-management

Cisco’s announcement that it will sunset Cisco Vulnerability Management (Kenna) marks a clear inflection point for many security teams. With end-of-sale and end-of-life timelines now defined, and no replacement offering on the roadmap, Kenna customers face an unavoidable decision window. 

Beyond the practical need to replace a tool, Kenna’s exit raises a bigger question for security leaders: what should vulnerability management look like moving forward? 

Not just a tool change

For many organizations, Kenna wasn’t “just another scanner”. Before their acquisition by Cisco in 2021, Kenna Security helped pioneer a shift away from chasing raw CVSS scores and toward prioritization based on real-world risk, influencing how many teams approach risk-based vulnerability management. Security teams invested years building workflows, reporting, and executive trust around that model. 

That’s why this moment feels different. Replacing Kenna isn’t about checking a feature box, it’s about protecting the integrity of the progress teams have already made while using this moment to elevate programs past traditional vulnerability management.

Security leaders are rightly cautious. No one wants to: 

  • Rush into a short-term replacement vs. a platform that suits current and future needs

  • Trade proven prioritization for untested promises 

  • Disrupt remediation workflows that engineering teams finally trust 

At the same time, few teams believe traditional vulnerability management – isolated scanners, static scoring, endless ticket queues – is sufficient on its own anymore. 

So where does that leave you? 

“Risk-based vulnerability management is dead” doesn’t tell the full story

In response to Kenna’s end-of-life, much of the market has rushed to frame this as the end of risk-based vulnerability management (RBVM) altogether. The message is often loud and binary: RBVM is outdated, jump straight to exposure management.

In practice, that framing doesn’t match how security programs actually evolve. 

Most organizations are not abandoning vulnerability management. They are expanding it:

  • From on-prem to hybrid and cloud

  • From isolated findings to broader attack surface context 

  • From vulnerability lists to exposure-driven decisions 

  • From static to continuous

The mistake is assuming this evolution requires a hard reset, or that exposure management is completely separate and not part of that evolution.  

For CISOs and hands-on leaders alike, the smarter question is: how do we preserve what works today, while building toward what we know we’ll need tomorrow?

What Kenna customers should prioritize next 

As you evaluate what comes after Kenna, the right decision comes down to which platform can consistently deliver security outcomes and measurable risk reduction: 

Continuity without disruption

Your team already understands risk-based prioritization. The next platform should strengthen that muscle, not force you back to severity-only thinking or one-dimensional scoring models that ignore business context and threat intelligence. 

See risk clearly across on-prem, cloud, and external environments

Risk doesn’t live exclusively on-prem or in the cloud. Vulnerability data needs to reflect the reality of modern environments – endpoints, cloud workloads, external-facing assets – without fragmenting visibility. It needs to build on what teams already have by supporting findings from a broad range of existing tools and services, so risk can be understood in one place instead of scattered across platforms. 

Customizable remediation workflows

Prioritization only matters if it leads to action. Look for platforms that help security and IT teams collaborate, track ownership, and measure progress without creating more friction. 

A credible path forward

Exposure management is valuable only when it’s grounded in accurate data, operational context, and day-to-day usability. Security teams are already drowning in findings across tools, and without context that explains what matters and why, exposure management adds more noise instead of helping teams make decisions and reduce risk. That noise shows up in familiar ways: duplicate findings aren’t reconciled, conflicting risk scores between tools, unclear ownership for remediation, and long lists of issues with no clear path to action.

Why this moment favors steady platforms, not big bets

Kenna’s exit creates pressure, but pressure shouldn’t drive risky or forced decisions. Security leaders are accountable not just for vision, but for outcomes, such as: 

  • Are we reducing real risk this quarter? 

  • Can we explain prioritization decisions to the board? 

  • Will this platform still support us two or three years from now? 

This is where vendor stability, roadmap clarity, and operational proof start to matter more than bold claims. 

The strongest next steps are coming from platforms that already deliver visibility across hybrid environments, mature, threat-informed vulnerability prioritization, and integrated remediation workflows that teams actually use. From there, exposure management becomes an evolution, not a leap of faith. 

A measured path forward

Kenna’s EOL doesn’t signal the end of risk-based vulnerability management. It signals that security programs are ready to expect more from it. For security leaders this is an opportunity to reaffirm what has worked in your program, close real visibility and workflow gaps, and choose a platform that supports both near-term continuity and long-term growth.

The goal isn’t to chase the next trend. It’s to make a confident, practical decision – one that protects today’s outcomes while positioning your team for what’s next. 

Looking ahead

If you’re navigating what comes after Cisco Kenna, the most important step is understanding your options early, before timelines force rushed decisions. Explore what a confident transition can look like and how teams are approaching continuity today while preparing for exposure management tomorrow. 

Explore a confident path forward.

Security updates for Tuesday

Post Syndicated from jzb original https://lwn.net/Articles/1056158/

Security updates have been issued by AlmaLinux (kernel, kernel-rt, python-urllib3, python3.11-urllib3, and python3.12-urllib3), Debian (imagemagick, openjdk-11, openjdk-17, and openjdk-21), Fedora (bind, bind-dyndb-ldap, chromium, ghostscript, glibc, mingw-glib2, mingw-harfbuzz, mingw-libsoup, mingw-openexr, and qownnotes), Mageia (kernel-linus), Red Hat (osbuild-composer), SUSE (go1.24-openssl, go1.25-openssl, govulncheck-vulndb, kernel, nodejs22, openCryptoki, openvswitch3, python-pyasn1, python311, and qemu), and Ubuntu (git-lfs, node-form-data, and screen).

Building a serverless, post-quantum Matrix homeserver

Post Syndicated from Nick Kuntz original https://blog.cloudflare.com/serverless-matrix-homeserver-workers/

Matrix is the gold standard for decentralized, end-to-end encrypted communication. It powers government messaging systems, open-source communities, and privacy-focused organizations worldwide. 

For the individual developer, however, the appeal is often closer to home: bridging fragmented chat networks (like Discord and Slack) into a single inbox, or simply ensuring your conversation history lives on infrastructure you control. Functionally, Matrix operates as a decentralized, eventually consistent state machine. Instead of a central server pushing updates, homeservers exchange signed JSON events over HTTP, using a conflict resolution algorithm to merge these streams into a unified view of the room’s history.

But there is a “tax” to running it
Traditionally, operating a Matrix homeserver has meant accepting a heavy operational burden. You aren’t just installing software; you are becoming a system administrator. You have to provision virtual private servers (VPS), tune PostgreSQL for heavy write loads, manage Redis for caching, configure reverse proxies, and handle rotation for TLS certificates. It’s a stateful, heavy beast that demands to be fed time and money, whether you are sending one message a day or one million.

We wanted to see if we could eliminate that tax entirely.

Spoiler: We could. In this post, we’ll explain how we ported a complete Matrix homeserver to Cloudflare Workers. The result is a serverless architecture where operations disappear, costs scale to zero when idle, and every connection is protected by post-quantum cryptography by default. You can view the source code and deploy your own instance directly from GitHub.

From Tuwunel to Workers

Our starting point was Tuwunel, a Rust-based Matrix homeserver designed for traditional deployments. PostgreSQL for persistence, Redis for caching, filesystem for media. Porting it to Workers meant questioning every storage assumption we’d taken for granted.

The good news: Rust compiles to WebAssembly, and the core Matrix protocol logic — event authorization, room state resolution, cryptographic verification — translated directly. The workers-rs crate bridges the gap to Cloudflare’s runtime.

The challenge was storage. Traditional homeservers assume strong consistency via a central SQL database. Cloudflare offers a powerful alternative: Durable Objects. This primitive gives us the strong consistency and atomicity required for Matrix state resolution, while still allowing the application to run at the edge.

Here’s how the mapping worked out:


From monolith to serverless

Moving to Cloudflare Workers brings several advantages for a developer: simple deployment, lower costs, low latency, and built-in security.

Easy deployment: A traditional Matrix deployment requires server provisioning, PostgreSQL administration, Redis cluster management, TLS certificate renewal, load balancer configuration, monitoring infrastructure, and on-call rotations.

With Workers, deployment is wrangler deploy. We handle TLS, load balancing, DDoS protection, and global distribution. So there’s no server to patch, no database to vacuum, or certificates to renew.

Usage-based costs: Traditional homeservers cost money whether anyone is using them or not. A small community server handling a few hundred requests per day still requires a typical VPS costing around $20/month running 24/7.

Workers pricing is request-based, so low-traffic homeservers cost just pennies. When usage spikes during active conversations, you pay for what you use. When everyone goes to sleep, costs drop toward zero.

Lower latency globally: A traditional Matrix homeserver in us-east-1 adds 200ms+ latency for users in Asia or Europe. Every sync request, message sent, and typing indicator go round-trip to a single region.

Workers, meanwhile, run in 300+ locations worldwide. When a user in Tokyo sends a message, the Worker executes in Tokyo. 

Built-in security: Matrix homeservers can be high-value targets: They handle encrypted communications, store message history, and authenticate users. Traditional deployments require careful hardening: firewall configuration, rate limiting, DDoS mitigation, WAF rules, IP reputation filtering.

We provide all of this by default. The Worker never sees attack traffic, because we filter it first. For a solo developer or small team, achieving this level of hardening on a Linux VPS is a full-time job. On Workers, it is the baseline environment.

Post-quantum protection without the complexity

Here’s something most Matrix operators don’t consider: harvest now, decrypt later.

An adversary captures your encrypted TLS traffic today and stores it. Years from now, when quantum computers can break classical key exchange algorithms, they decrypt everything retroactively. For a messaging platform handling sensitive communications, this isn’t theoretical. Government agencies and well-funded adversaries are already stockpiling encrypted traffic.

Fortunately, we didn’t have to protect against this by ourselves. Cloudflare deployed post-quantum hybrid key agreement across all TLS 1.3 connections in October 2022. Every connection to our Worker automatically negotiates X25519MLKEM768 — a hybrid combining classical X25519 with ML-KEM, the post-quantum algorithm standardized by NIST.

Classical cryptography relies on mathematical problems that are hard for traditional computers but trivial for quantum computers running Shor’s algorithm. ML-KEM is based on lattice problems that remain hard even for quantum computers. The hybrid approach means both algorithms must fail for the connection to be compromised.

Following a message through the system

Understanding where encryption happens matters for security architecture. When someone sends a message through our homeserver, here’s the actual path:

The sender’s client takes the plaintext message and encrypts it with Megolm — Matrix’s end-to-end encryption. This encrypted payload then gets wrapped in TLS for transport. On Cloudflare, that TLS connection uses X25519MLKEM768, making it quantum-resistant.


The Worker terminates TLS, but what it receives is still encrypted — the Megolm ciphertext. We store that ciphertext in D1, index it by room and timestamp, and deliver it to recipients. But we never see the plaintext. The message “Hello, world” exists only on the sender’s device and the recipient’s device.

When the recipient syncs, the process reverses. They receive the encrypted payload over another quantum-resistant TLS connection, then decrypt locally with their Megolm session keys.

Two layers, independent protection

This creates defense in depth through two encryption layers that operate independently:

The transport layer (TLS) protects data in transit. It’s encrypted at the client and decrypted at the Cloudflare edge. With X25519MLKEM768, this layer is now post-quantum.

The application layer (Megolm E2EE) protects message content. It’s encrypted on the sender’s device and decrypted only on recipient devices. This uses classical Curve25519 cryptography.

Here’s why this architecture matters: Even if Matrix E2EE is eventually broken by quantum computers, the message content was never transmitted in a quantum-vulnerable form. The TLS layer that carried the E2EE ciphertext was itself post-quantum secured.

The post-quantum TLS acts as a quantum-resistant envelope around everything, including the classical E2EE layer. This buys time for the Matrix protocol to migrate to post-quantum E2EE algorithms without leaving current communications vulnerable to harvest-now-decrypt-later attacks.

Who sees what

Any Matrix homeserver operator — whether running Synapse on a VPS or this implementation on Workers — can see metadata: which rooms exist, who’s in them, when messages were sent. This is inherent to operating the server. You’re the operator; you control the infrastructure.

What no one in the infrastructure chain can see: message content. The E2EE payload is encrypted on sender devices before it ever hits the network. Cloudflare terminates TLS and passes requests to your Worker, but both see only Megolm ciphertext. Media in encrypted rooms is encrypted client-side before upload. Private keys never leave user devices.

The server processes ciphertext, not conversations. That’s true whether you’re self-hosting on bare metal or running on Workers.

What traditional deployments would need

Achieving post-quantum TLS on a traditional Matrix deployment would require upgrading OpenSSL or BoringSSL to a version supporting ML-KEM, configuring cipher suite preferences correctly, testing client compatibility across all Matrix apps, monitoring for TLS negotiation failures, staying current as PQC standards evolve, and handling clients that don’t support PQC gracefully.

With Workers, it’s automatic. Chrome, Firefox, and Edge all support X25519MLKEM768. Mobile apps using platform TLS stacks inherit this support. The security posture improves as Cloudflare’s PQC deployment expands — no action required on our part.

The storage architecture that made it work

The key insight from porting Tuwunel was that different data needs different consistency guarantees. We use each Cloudflare primitive for what it does best.

D1 for the data model

D1 stores everything that needs to survive restarts and support queries: users, rooms, events, device keys. Over 25 tables covering the full Matrix data model.

CREATE TABLE events (
	event_id TEXT PRIMARY KEY,
	room_id TEXT NOT NULL,
	sender TEXT NOT NULL,
	event_type TEXT NOT NULL,
	state_key TEXT,
	content TEXT NOT NULL,
	origin_server_ts INTEGER NOT NULL,
	depth INTEGER NOT NULL
);

D1’s SQLite foundation meant we could port Tuwunel’s queries with minimal changes. Joins, indexes, and aggregations work as expected.

We learned one hard lesson: D1’s eventual consistency breaks foreign key constraints. A write to rooms might not be visible when a subsequent write to events checks the foreign key — different replicas, different views of the world. We removed all foreign keys and enforce referential integrity in application code.

KV for ephemeral state

OAuth authorization codes live for 10 minutes. Refresh tokens last for a session. None of this needs SQL — it needs fast key-value access with automatic expiration.

// Store OAuth code with 10-minute TTL
kv.put(&format!("oauth_code:{}", code), &token_data)?
	.expiration_ttl(600)
	.execute()
	.await?;

KV’s global distribution means OAuth flows work fast regardless of where users are located.

R2 for media

Matrix media maps directly to R2. Upload an image, get back a content-addressed URL. Egress is free, which matters for a protocol where clients frequently download the same avatars and images.

Durable Objects for atomicity

Some operations can’t tolerate eventual consistency. When a client claims a one-time encryption key, that key must be atomically removed. If two clients claim the same key, encrypted session establishment fails.

Durable Objects provide single-threaded, strongly consistent storage:

#[durable_object]
pub struct UserKeysObject {
	state: State,
	env: Env,
}

impl UserKeysObject {
	async fn claim_otk(&self, algorithm: &str) -> Result<Option<Key>> {
    	// Atomic within single DO - no race conditions possible
    	let mut keys: Vec<Key> = self.state.storage()
        	.get("one_time_keys")
        	.await
        	.ok()
        	.flatten()
        	.unwrap_or_default();

    	if let Some(idx) = keys.iter().position(|k| k.algorithm == algorithm) {
        	let key = keys.remove(idx);
        	self.state.storage().put("one_time_keys", &keys).await?;
        	return Ok(Some(key));
    	}
    	Ok(None)
	}
}

We use UserKeysObject for E2EE key management, RoomObject for real-time room events like typing indicators and read receipts, and UserSyncObject for to-device message queues. The rest flows through D1.

Complete E2EE, complete OAuth

End-to-end encryption is non-negotiable for secure communications. Our implementation supports the full Matrix E2EE stack: device keys, cross-signing keys, one-time keys, fallback keys, key backup, and dehydrated devices.

Modern Matrix clients use OAuth 2.0/OIDC instead of legacy password flows. We implemented a complete OAuth provider: dynamic client registration, PKCE authorization, RS256-signed JWT tokens, token refresh with rotation, and standard OIDC discovery endpoints.

curl https://matrix.example.com/.well-known/openid-configuration
{
  "issuer": "https://matrix.example.com",
  "authorization_endpoint": "https://matrix.example.com/oauth/authorize",
  "token_endpoint": "https://matrix.example.com/oauth/token",
  "jwks_uri": "https://matrix.example.com/.well-known/jwks.json"
}

Point Element or any Matrix client at the domain, and it discovers everything automatically.

Sliding Sync for mobile

Traditional Matrix sync transfers megabytes of data on initial connection — every room, every state event, recent timeline for each. This destroys mobile battery and data plans.

Sliding Sync lets clients request exactly what they need. Instead of downloading everything, clients get the 20 most recent rooms with minimal state. As users scroll, they request more ranges. The server tracks position and sends only deltas.

Combined with edge execution, mobile clients can connect and render their room list in under 500ms — even on slow networks.

The comparison

For a homeserver serving a small team:


Traditional (VPS)

Workers

Monthly cost (idle)

$20-50

<$1

Monthly cost (active)

$20-50

$3-10

Global latency

100-300ms

20-50ms

Time to deploy

Hours

Seconds

Maintenance

Weekly

None

DDoS protection

Additional cost

Included

Post-quantum TLS

Complex setup

Automatic

*Based on public rates and metrics published by DigitalOcean, AWS Lightsail, and Linode as of January 15, 2026.

The economics improve further at scale. Traditional deployments require capacity planning and over-provisioning. Workers scale automatically.

The future of decentralized protocols

When we started this project, the goal was simply to see if the pieces would fit. Could a protocol as complex and stateful as Matrix — designed for heavy iron and persistent file systems — actually run on an ephemeral, serverless edge?

The answer is yes, but the implication is bigger than just Matrix.

By mapping traditional stateful components to Cloudflare’s primitives — Postgres to D1, Redis to KV, mutexes to Durable Objects — we proved that complex applications don’t need complex infrastructure. We stripped away the operating system, the database management, and the network configuration, leaving only the application logic and the data itself.

This architecture shifts the paradigm for self-hosting. It turns “running a server” from a chore into a utility. You get the sovereignty of owning your data without the burden of owning the infrastructure.

Matrix on Workers runs in production today, handling real encrypted communications for our team. It is fast, it is cheap, and it is arguably one of the most secure ways to deploy a homeserver today.

Ready to build secure, real-time applications on Workers? Get started with Cloudflare Workers and explore Durable Objects for your own stateful edge applications. Join our Discord community to connect with other developers building at the edge.

The Constitutionality of Geofence Warrants

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/01/the-constitutionality-of-geofence-warrants.html

The US Supreme Court is considering the constitutionality of geofence warrants.

The case centers on the trial of Okello Chatrie, a Virginia man who pleaded guilty to a 2019 robbery outside of Richmond and was sentenced to almost 12 years in prison for stealing $195,000 at gunpoint.

Police probing the crime found security camera footage showing a man on a cell phone near the credit union that was robbed and asked Google to produce anonymized location data near the robbery site so they could determine who committed the crime. They did so, providing police with subscriber data for three people, one of whom was Chatrie. Police then searched Chatrie’s home and allegedly surfaced a gun, almost $100,000 in cash and incriminating notes.

Chatrie’s appeal challenges the constitutionality of geofence warrants, arguing that they violate individuals’ Fourth Amendment rights protecting against unreasonable searches.

How to strategically plan your computing curriculum

Post Syndicated from Sean Sayers original https://www.raspberrypi.org/blog/how-to-strategically-plan-your-computing-curriculum/

Traditionally, curriculum planning has often looked like a linear list: Topic A leads to Topic B, which leads to Topic C. However, as educators we know that learning rarely happens in such a simple, linear way. Concepts are regularly covered in different overlapping topics, and students can often take different routes to reach the same destination.

Image displaying the Learning Graphs Quick Read.

In today’s blog we’re exploring learning graphs, a helpful tool that you can use to plan your computer science curriculum. We’ll share how they can provide educators with a clear, structured way to visualise students’ non-linear progression in a subject.

We also share our new Pedagogy Quick Read about learning graphs, which you can download for free to:

  • Find practical tips on how you can use learning graphs to design your curriculum
  • Read a summary of the research behind them

What is a learning graph?

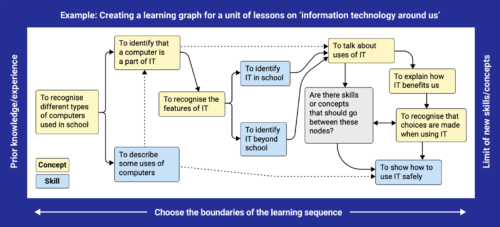
A learning graph is a visual tool for curriculum planning that moves beyond simple lists. At its core, a learning graph is a network of ‘nodes’ (specific concepts and skills) and ‘links’ (the connections between them).

Image from the Learning Graphs Quick Read that showcases an example of a learning graph.

Learning graphs build on research into ‘learning progressions’ and ‘knowledge maps’. They are a practical tool that educators can use to design and validate different curricula. For example, they can help teachers to:

  • Visualise and map progression
  • Identify curriculum gaps, so educators can shape and restructure learning experiences as necessary
  • Ensure the use of consistent terminology
  • Sequence learning and manage cognitive load

How to create a learning graph

Building a learning graph is an iterative process that helps you think critically about how different parts of your curriculum relate to each other.

Nodes and links

The first step in creating a learning graph is often to identify your start and end nodes. First, you consider the key concepts and skills that your learners must acquire by the end of a series of lessons. This gives you some end nodes to work towards. Then, you think about learners’ existing knowledge, to help determine your start point. You then work backwards and forwards between these points to identify the different nodes that learners need to cover to get from the beginning to the end.

Educators sharing ideas around a table.

Once you have determined your nodes, you add them to your graph and connect them via ‘links’ until your graph is complete. Where knowledge of particular concepts or skills is essential for learning others, you connect the nodes with solid lines. For prior learning that is helpful but not essential, you use dotted lines.

When developing a learning graph, there isn’t a specific level of granularity that you have to work towards. Progression can be as detailed or as high-level as you need. This makes them a helpful tool in creating bespoke learning experiences and curricula for learners.

Collaboration and development

It is most effective to design learning graphs collaboratively within a small group. This allows curriculum designers to discuss their ideas and challenge each other’s thinking, which helps hone the designs.

Educators collaborating using post-it notes, planning currciulum.

When creating learning graphs, it can be extremely useful to use a tool that is dynamic and allows you to move elements and make changes quickly and easily. At the Raspberry Pi Foundation, our team has experimented with a range of tools, including using editable shapes in Google Slides, collaborating in Figma, and arranging sticky notes on paper. We recommend finding a tool that works for you and the educators you are working with. Although it can work, we suggest avoiding using a pen and paper if possible, as designs can quickly become messy and difficult to navigate after lots of iterations.

The process of designing learning graphs has strong links to ABC learning design and the creation of concept maps, which can also be used for curriculum planning.

Learning graphs in your teaching

Once created, learning graphs can support you to design and adapt your curricula and assess your students’ learning.

For example, to help sequence learning, you can track or predict the paths through a topic most commonly taken by learners and use this to inform your curriculum design.

If you are adapting a unit of work for a specific qualification or new context, you can prune nodes that are not relevant and add any further knowledge and skills your learners need, then use the new learning graph to guide you as you develop the unit.

Finally, you can assess which node a learner has completed, and use this to identify the next logical step in their learning, ensuring the difficulty level is always appropriate.

Using learning graphs to support analysis

Another benefit of learning graphs is that they can be combined with lots of other frameworks, for example, Bloom’s taxonomy. This allows you to better assess and validate the learning journeys you have designed, and ensure that they are suitably accessible, challenging, and relevant for your learners.

Photo of an educator presenting at the front of a classroom of other teachers.

There are a number of ways that you could link your learning graphs to other frameworks, such as annotating nodes with extra information, or using colour coding.

As well as working with learning graphs for specific learning experiences, you can connect multiple learning graphs together and analyse how they intersect. This can help identify inconsistencies between connected sequences of lessons. It can also help uncover broader themes of progression and highlight alternative learning pathways you might not have considered.

Find out more about learning graphs

If you’d like to find out more about learning graphs, you can download our Pedagogy Quick Read for free.

To find out more about how we use learning graphs when planning curriculum resources at the Raspberry Pi Foundation, take a look at our teaching and learning design principles.

The post How to strategically plan your computing curriculum appeared first on Raspberry Pi Foundation.

Облаче ле бяло

Post Syndicated from original https://www.toest.bg/oblache-le-byalo/

Облаче ле бяло

2025-та вече е зад нас, а заедно с нея и цветът на годината, който, макар и наречен с изтънчено звучащото наименование Mocha Mousse („мока мус“), на вид по-скоро напомня оттичаща се в канализацията отпадъчна материя. С настъпването на новата година обаче сме поканени оптимистично да обърнем взор нагоре към небето (и да заровим глави в речниците).

За цвят на 2026-та Pantone Color Institute обяви т.нар. Cloud Dancer, чието наименование българските медии превеждат като „облачно бяло“,

въпреки че думата „бяло“ очевидно отсъства в „оригинала“ и по-точният му превод е нещо като „танцьор в облаците“. Описан като мек, неутрален, въздушен нюанс (който на български би могъл да се определи и със злощастното название „мръснобяло“), според Pantone идеята е цветът да символизира спокойствие, простота, яснота, релаксация и както подобава на всеки старт на годината – ново начало.

Горното описание, обобщено от многобройните медийни съобщения по темата, демонстрира удивителната способност на компанията да приписва на цветовете характеристики, които не са им естествено присъщи непременно. Освен чрез засуканите наименования Pantone постига това и с високопарните описания, които придружават анонсирането на всеки цвят и с всяка изминала година все повече наподобяват – както личи от най-новия избор – въздух под налягане.

Така например лаици като мен и вас биха помислили, че през последните 26 години, откакто датира традицията, оранжевото (макар и в различни нюанси) е било цвят на годината цели четири пъти. Да, ама не: според Pantone цветът на 2004 г. е Tigerlily („тигров лилиум“) – „ярък, смел, страстен и подмладяващ“; на 2012 г. той е Tangerine Tango („мандаринено танго“) – „магнетичен оттенък, който напомня за сияйните нюанси на залеза и излъчва топлина и енергия“; на 2019 г. е Living Coral („жив корал“) – „оживяващ и жизнеутвърждаващ коралов оттенък със златист подтон, който енергизира и съживява“; а на 2024 г. е Peach Fuzz („прасковен мъх“) – „топъл и уютен оттенък между розово и оранжево с винтидж атмосфера, който носи усещане за нова модерност и нежност, както и послание за грижа и споделяне, общност и сътрудничество“. 

Подобна е ситуацията и със сините, розовите и зелените разцветки, разновидности на които неколкократно са избирани за цвят на годината. Бялото, в какъвто и да било нюанс, оглавява класацията за първи път. Като за цвят, който в същността си представлява липса на цветове, изборът на Pantone за 2026 г. предизвиква множество критики – те варират от твърдения, че бялото е скучно и безлично, до обвинения в „далтонизъм“¹ по отношение на съвсем небезобидните обществени трусове, геополитически проблеми и икономически предизвикателства, с които в момента се сблъсква светът.

В това отношение

цветовете са като думите – те притежават нюанси, предизвикват лични асоциации и носят разнообразни конотации според контекста,

които не могат да бъдат изцяло наложени отвън. Това важи с особена сила за белия цвят, който всъщност съдържа в себе си всички останали цветове. Подобно на табула раза, върху него може да се проектират всякакви, често противоположни смисли и значения. Защото бялото – освен невинност (в булчинската рокля), чистота и духовност (в одеждите на дъновистите или на папата) или ново началото (на белия лист) – също така би могло да символизира траур (в източните традиции), капитулация (в бялото знаме), расизъм и вяра в превъзходството на белите (в мантиите на Ку-клукс-клан).

По сходен начин думата „облак“ също съдържа „цял спектър“ от възможни значения и конотации. Освен приписаните му от Pantone лекота, ефирност и мекота, облакът може да означава и много други, не непременно възвишени неща: непостоянство и разсеяност, замъгленост и неяснота, мрачно предзнаменование и заплаха. Както и място за съхранение на дигитални данни. Или пък мента с мастика.

Ако пък въпросният облак, освен бял, е и в умалителна форма, много българи със сигурност биха го свързали с носталгия по родината.

Лично аз винаги се сещам за трогателното, каращо ме да настръхна изпълнение на „Облаче ле бяло“ на Силви Вартан.

В този текст ще се опитам да отговоря на въпроса, с който започва песента – „Я кажи ми, облаче ле бяло, /отде идеш, де си ми летяло?“, – но от етимологична гледна точка. Освен коренно различните разбирания за това какво представляват облаците, проследяването на произхода на думата през различни древни или праезици, а оттам и до техните съвременни наследници разкрива доста любопитни семантични взаимовръзки както между езиците, така и вътре в самите тях. Макар и заобиколно, част от нишките водят и до българския.

В романските езици думите за „облак“ – nuage на френски, nuvola на италиански, nube на испански, nor на румънски – неизненадващо, произлизат от латинския. Изненадващото в случая е, че същият латински корен – nubes („облак“) – е в основата и на дума, която през френския е навлязла и в българския, а в този текст е особено актуална и се появява многократно: това е думата „нюанс“.

Въпреки сходното произношение и семантика латинската дума nubes, която произлиза от праиндоевропейския глагол *(s)newdʰ- („покривам“), не споделя родство с латинското название nebula („мъгла“)² – то произлиза от праиндоевропейската дума *nébʰos („облак“). Именно тя стои и в основата на славянските вариации на думата „небе“.

От същия праиндоевропейски корен произлизат и двете думи за „облак“, които се срещат както в древния, така и в съвременния гръцки език– νέφος (néfos) и νεφέλη (neféli). Сходното звучене, както и концептуално близките значения тук също могат да ни подведат, че от тези понятия произлиза чудесната дума „нефелен“. Българският етимологичният речник обаче опровергава тези очаквания, като проследява произхода ѝ до прилагателното ανωφελής (anofelís), което има друг корен и означава „безполезен“.

Думата „облак“ в българския и в останалите славянски езици има праславянски корени – *obolkъ, от представката *оb– („около“) + *volk- („тегля, влача“), – като по този начин споделя сходна етимология с глагола „обличам“.³

Макар, че названието присъства с малки вариации във всички славянски езици, някои от тях разполагат с допълнителни думи, с които обозначават струпаните водни пари в атмосферата. Чешкият например прави разлика между белия, незаплашителен oblak и тъмния, буреносен mrak. На полски думата obłok се смята за по-поетична и „възвишена“, докато всекидневната дума е chmura. „Хмара“ означава „облак“ и на украински. Макар да не присъства нито в моя личен речник, нито в тълковния речник на БАН, според bgjargon.com тази дума съществува и в българския език със следната дефиниция: „гъста пушилка, думан, сумрак; нещо непрогледно и мрачно“.

Произходът на днешната английска дума за „облак“ също е доста далечен – както концептуално, така и пространствено – от ефирния cloud в наименованието на Pantone: първоначалното значение на староанглийската дума clud е ‘скала, камък, буца пръст, маса’ и няма нищо общо с небето. С развитието на езика обаче значението ѝ се разширява и става метафорично, докато към края на XV век, с преминаването към ранния модерен английски, идеята за земната маса отпада изцяло и се заменя с концепцията за небесната⁴.

Съвременната английска дума sky, тоест „небе“, претърпява паралелна трансформация. Наследена от староскандинавски, първоначално тя навлиза със значението „облак“, което в (почти) всички скандинавски езици се запазва и до днес⁵. С течение на времето обаче смисълът ѝ се променя и тя постепенно измества напълно двете староанглийски думи за „небе“: heofon, откъдето идва съвременната дума heaven („рай“), и weolcan („облак, небе“), която произлиза от прагерманската *wulkną, откъдето пък идва съвременната немска дума за „облак“ – Wolke. (И тук, съвсем ненадейно, откриваме връзка с българския през общия праиндоевропейски корен *wl̥g-nó-s, откъдето произлиза праславянската дума *volga, като реката, а оттам и съвременната „влага“.)

Както личи от горните примери, понятията за „облак“ и „небе“ често са свързани, а нерядко се и припокриват. Чешкият предоставя интересен пример за това – освен двете думи за „облак“, споменати по-горе, в него има и две отделни названия за „небе“: nebe – с по-абстрактно значение, и obloha, което се използва в буквален смисъл. Ето как „В небето има облаци“ на чешки би могло да изглежда така: Na obloze jsou oblaky. Или пък така: Na nebi jsou mraky.

Особено забавни в това отношение са и калките на американската дума skyscraper в различните езици. Някои от тях остават верни на оригинала, като двете съставни части се превеждат буквално, например българският „небостъргач“, сръбският „небодер“, литовският dangoraižis, турският gökdelen и гръцкият ουρανοξύστης (ouranoxýstis), макар и понякога местата на корените да се разменят, като във френския gratte-ciel, испанския rascacielos и румънския zgârie-nori. В други езици се прилага по-свободен подход и думата „небе“ се заменя с „облак“, например в немския Wolkenkratzer, унгарския felhőkarcoló, финландския pilvenpiirtäjä, както и в личните ми фаворити – украинския „хмарочос“, чешкия mrakodrap и македонския „облакодер“. Положението става съвсем хаотично в скандинавските езици (skyskraper на норвежки, skyskraber на датски и skýjakljúfur на исландски), които хем уж запазват англоезичното „небе“, хем всъщност разчитат на оригиналното значение на думата като „облак“. На шведски названието е skyskrapa, обаче там случаят е специален, тъй като sky (произнася се като „хуѝ“) се използва рядко, но има идентично значение с думата в английския.

За концептуалната и семантична взаимосвързаност (нерядко до степен на взаимозаменяемост) между облаците и небето свидетелства и изразът „седмото небе“ и итерациите му на различни езици. Облаците присъстват в еквивалентните изрази на английски – to be on cloud nine, на немски – auf Wolke sieben sein, на френски – être sur un petit nuage, докато в българския и в много други езици от различни семейства изразът за върховно щастие препраща към небето, и то конкретно към седмото: být v sedmém nebi (чешки), essere al settimo cielo (италиански), vara i sjunde himlen (шведски), في السماء السابعة (арабски), בַּשָּׁמַיִם הַשְּׁבִיעִים (иврит).

От горните примери се вижда, че докато повечето езици използват числото седем (без значение дали във връзка с облак, или с небе), в английския облакът на блаженството е заведен под номер девет (макар че и там съществува вече остарелият и далеч не толкова популярен идиом seventh heaven).

Седмѝцата може да се обясни с древната символика и значение на числото в християнската, ислямската и еврейската традиция. За разлика от това число, деветката в английския израз има много по-нов и не съвсем ясен произход. Според широко разпространената теория тя е заимствана от Международния атлас на облаците, първоначално издаден през 1896 г., където са описани десет вида облаци – деветият от тях е т.нар. cumulonimbus, който се издига най-високо в атмосферата и изглежда най-голям, пухкав и комфортен. Изборът на точно този вид облак като синоним за блаженство обаче е озадачаващ, като се вземе предвид, че наименованието му означава „купесто-дъждовен“ и че точно той поражда мълнии, гръмотевични бури, проливни дъждове, смерчове и други опасни метеорологични условия.

Тепърва предстои да видим

дали тази година ще танцуваме на деветия облак, на облак номер 11-4201 TCX (както е обозначен Cloud Dancer на Pantone), или в деветия кръг на ада.

Едно обаче е сигурно: годината несъмнено ще е облачна. Но нека бъдем оптимисти и да се надяваме, че английската поговорка every cloud has a silver lining, която произлиза от творба на Джон Милтън и буквално означава, че всеки облак има сребърен хастар, ще се окаже вярна – тоест че всяко зло наистина ще е за добро. Все пак дори Дантевият „Ад“ завършва с надеждата, че след преминаването през деветия кръг отново ще видим звездите.

1 Терминът „далтонизъм“, вероятно навлязъл в българския език от френския, произлиза от името на английския химик Джон Далтон, който сам е страдал от това зрително нарушение и първи го е описал. Подобно на наименованията на облаците, които съществуват в разговорна и в латинска форма, зрителният дефект, водещ до неспособността да се разграничават определени цветове, има още две наименования: „цветна слепота“ и „дисхроматопсия“.

2 От латинската дума nebula произлиза и английското прилагателно nebulous, което най-често се използва преносно и означава ‘неясен, мъгляв, неопределен’. Макар че то не е навлязло в говоримия български език, астрономите използват термина „небуларен“, който се отнася за космическите мъглявини.

3 Освен „облак“, от същия праславянски корен – *volk- (‘тегля, влача’) – произлиза и думата „влак“. Праиндоевропейският му родител *welk- пък е в основата на английския глагол walk (‘ходя’). Сходна идея присъства и в думата за „облак“ на арабски (سحاب/saḥāb), която произлиза от корен, означаващ ‘издърпване, влачене’.

4 Въпреки трансформацията в значението на думата clud, в съвременния английския се срещат редица думи, чието значение е свързано с оригиналното значение на думата (‘скала, камък, буца пръст, маса’), като например clod и clump (и двете със значение ‘буца’), clot (‘съсирек’) и cluster (‘струпване’).

5 Sky означава „облак“ на всички скандинавски езици с изключение на шведския, където думата, макар че се смята за остаряла, се възприема по-скоро с англоезичното значение на „небе“, докато съвременната дума за „облак“ е moln. Тя, за съжаление, не е етимологично свързана с българската „мълния“, но нейният праславянски предшественик (*mъldni) все пак споделя праиндоевропейски корен (*meldʰ-) с друго скандинавско наименование, а именно Mjǫllnir – магическия чук на Тор, нордическия бог на гръмотевиците, светкавиците и бурите.

В рубриката „От дума на дума“ Екатерина Петрова търси актуални, интересни или новопоявили се думи от нашето ежедневие и проследява често изненадващия им произход, развитието на значенията им във времето и взаимовръзките им с близки и далечни езици.

Introducing Amutable

Post Syndicated from Lennart Poettering original https://0pointer.net/blog/introducing-amutable.html

Today, we announce Amutable, our ✨ new ✨ company. We –
@[email protected],
@[email protected],
@[email protected],
@[email protected],
@[email protected],
@[email protected],
@[email protected],
@[email protected]
@[email protected],
@[email protected] and yours
truly
– are building the 🚀 next generation
of Linux systems, with integrity, determinism, and verification – every step of
the way.

For more information see → https://amutable.com/blog/introducing-amutable

IAM Identity Center now supports IPv6

Post Syndicated from Suchintya Dandapat original https://aws.amazon.com/blogs/security/iam-identity-center-now-supports-ipv6/

Amazon Web Services (AWS) recommends using AWS IAM Identity Center to provide your workforce access to AWS managed applications—such as Amazon Q Developer—and AWS accounts. Today, we announced IAM Identity Center support for IPv6. To learn more about the advantages of IPv6, visit the IPv6 product page.

When you enable IAM Identity center, it provides an access portal for workforce users to access their AWS applications and accounts either by signing in to the access portal using a URL or by using a bookmark for the application URL. In either case, the access portal handles user authentication before granting access to applications and accounts. Supporting both IPv4 and IPv6 connectivity to the access portal helps facilitate seamless access for clients, such as browsers and applications, regardless of their network configuration.

The launch of IPv6 support in IAM Identity Center introduces new dual-stack endpoints that support both IPv4 and IPv6, so that users can connect using IPv4, IPv6, or dual-stack clients. Current IPv4 endpoints continue to function with no action required. The dual stack capability offered by Identity Center extends to managed applications. When users access the application dual-stack endpoint, the application automatically routes to the Identity Center dual-stack endpoint for authentication. To use Identity Center from IPv6 clients, you must direct your workforce to use the new dual-stack endpoints, and update configurations on your external identity provider (IdP), if you use one.

In this post, we show you how to update your configuration to allow IPv6 clients to connect directly to IAM Identity Center endpoints without requiring network address translation services. We also show you how to monitor which endpoint users are connecting to. Before diving into the implementation details, let’s review the key phases of the transition process.

Transition overview

To use IAM Identity Center from an IPv6 network and client, you need to use the new dual-stack endpoints. Figure 1 shows what the transition from IPv4 to IPv6 over dual-stack endpoints looks like when using Identity Center. The figure shows:

  • A before state where clients use the IPv4 endpoints.
  • The transition phase, when your clients use a combination of IPv4 and dual-stack endpoints.
  • After the transition is complete, your clients will connect to dual-stack endpoints using their IPv4 or IPv6, depending on their preferences.

Figure 1: Transition from IPv4-only to dual-stack endpoints

Figure 1: Transition from IPv4-only to dual-stack endpoints

Prerequisites

You must have the following prerequisites in place to enable IPv6 access for your workforce users and administrators:

  • An existing IAM Identity Center instance
  • Updated firewalls or gateways to include the new dual-stack endpoints
  • IPv6 capable clients and networks

Work with your network administrators to update the configuration of your firewalls and gateways and to verify that your clients, such as laptops or desktops, are ready to accept IPv6 connectivity. If you have already enabled IPv6 connectivity for other AWS services, you might be familiar with these changes. Next, implement the two steps that follow.

Step 1: Update your IdP configuration

You can skip this step If you don’t use an external IdP as your identity source.

In this step, you update the Assertion Consumer Service (ACS) URL from your IAM Identity Center instance into your IdP’s configuration for single sign-on and the SCIM configuration for user provisioning. Your IdP’s capability determines how you update the ACS URLs. If your IdP supports multiple ACS URLs, configure both IPv4 and dual-stack URLs to enable a flexible transition. With that configuration, some users can continue using IPv4-only endpoints while others use dual-stack endpoints for IPv6. If your IdP supports only one ACS URL, to use IPv6 you must update the new dual-stack ACS URL in your IdP and transition all users to using dual-stack endpoints. If you don’t use an external IdP, you can skip this step and go to the next step.

Update both the SAML single sign-on and the SCIM provisioning configurations:

  1. Update the single sign-on settings in your IdP to use the new dual-stack URLs. First, locate the URLs in the AWS Management Console for IAM Identity Center.
    1. Choose Settings in the navigation pane and then select Identity source.
    2. Choose Actions and select Manage authentication.
    3. in Under Manage SAML 2.0 authentication, you will find the following URLs under Service provider metadata:
      • AWS access portal sign-in URL
      • IAM Identity Center Assertion Consumer Service (ACS) URL
      • IAM Identity Center issuer URL
  2. If your IdP supports multiple ACS URLs, then add the dual-stack URL to your IdP configuration alongside existing IPv4 one. With this setting, you and your users can decide when to start using the dual-stack endpoints, without all users in your organization having to switch together.

    Figure 2: Dual-stack single sign-on URLs

    Figure 2: Dual-stack single sign-on URLs

  3. If your IdP does not support multiple ACS URLs, replace the existing IPv4 URL with the new dual-stack URL, and switch your workforce to use only the dual-stack endpoints.
  4. Update the provisioning endpoint in your IdP. Choose Settings in the navigation pane and under Identity source, choose Actions and select Manage provisioning. Under Automatic provisioning, copy the new SCIM endpoint that ends in api.aws. Update this new URL in your external IdP.

    Figure 3: Dual-stack SCIM endpoint URL

    Figure 3: Dual-stack SCIM endpoint URL

Step 2: Locate and share the new dual-stack endpoints

Your organization needs two kinds of URLs for IPv6 connectivity. The first is the new dual-stack access portal URL that your workforce users use to access their assigned AWS applications and accounts. The dual-stack access portal URL is available in the IAM Identity Center console, listed as the Dual-stack in the Settings summary (you might need to expand the Access portal URLs section, shown in Figure 4).

Figure 4: Locate dual-stack access portal endpoints

Figure 4: Locate dual-stack access portal endpoints

This dual-stack URL ends with app.aws as its top-level domain (TLD). Share this URL with your workforce and ask them to use this dual-stack URL to connect over IPv6. As an example, if your workforce uses the access portal to access AWS accounts, they will need to sign in through the new dual-stack access portal URL when using IPv6 connectivity. Alternately, if your workforce accesses the application URL, you need to enable the dual-stack application URL following application-specific instructions. For more information, see AWS services that support IPv6.

The URLs that administrators use to manage IAM Identity Center are the second kind of URL your organization needs. The new dual-stack service endpoints end in api.aws as their TLD and are listed in the Identity Center service endpoints. Administrators can use these service endpoints to manage users and groups in Identity Center, update their access to applications and resources, and perform other management operations. As an example, if your administrator uses identitystore.{region}.amazonaws.com to manage users and groups in Identity Center, they should now use the dual-stack version of the same service endpoint which is identitystore.{region}.api.aws, so they can connect to service endpoints using IPv6 clients and networks.

If your users or administrators use an AWS SDK to access AWS applications and accounts or manage services, follow Dual-stack and FIPS endpoints to enable connectivity to the dual-stack endpoints.

After completing these two steps, your workforce and administrators can connect to IAM Identity Center using IPv6. Remember, these endpoints also support IPv4, so clients not yet IPv6-capable can continue to connect using IPv4.

Monitoring dual-stack endpoint usage

You can optionally monitor AWS CloudTrail logs to track usage of dual-stack endpoints. The key difference between IPv4-only and dual-stack endpoint usage is the TLD and appears in the clientProvidedHostHeader field. The following example shows the difference between these CloudTrail events for the CreateTokenWithIAM API call.

IPv4-only endpoints Dual-stack endpoints
"CloudTrailEvent": {
  "eventName": "CreateToken",
  "tlsDetails": {
     "tlsVersion": "TLSv1.3",
     "cipherSuite": "TLS_AES_128_GCM_SHA256",
     "clientProvidedHostHeader": "oidc.us-east-1.amazonaws.com"
  }
}

"CloudTrailEvent": {
  "eventName": "CreateToken",
  "tlsDetails": {
     "tlsVersion": "TLSv1.3",
     "cipherSuite": "TLS_AES_128_GCM_SHA256",
     "clientProvidedHostHeader": "oidc.us-east-1.api.aws"
  }
}

Conclusion

IAM Identity Center now allows clients to connect over IPv6 natively with no network address translation infrastructure. This post showed you how to transition your organization to use IPv6 with Identity Center and its integrated applications. Remember that existing IPv4 endpoints will continue to function, so you can transition at your own pace. Also, no immediate action is required by you. However, we recommend planning your transition to take advantage of IPv6 benefits and meet compliance requirements. If you have questions, comments, or concerns, contact AWS Support, or start a new thread in the IAM Identity Center re:Post channel.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Suchintya Dandapat
Suchintya Dandapat

Suchintya Dandapat is a Principal Product Manager for AWS where he partners with enterprise customers to solve their toughest identity challenges, enabling secure operations at global scale.

The AI Evolution of Graph Search at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/the-ai-evolution-of-graph-search-at-netflix-d416ec5b1151

The AI Evolution of Graph Search at Netflix: From Structured Queries to Natural Language

By Alex Hutter and Bartosz Balukiewicz

Our previous blog posts (part 1, part 2, part 3) detailed how Netflix’s Graph Search platform addresses the challenges of searching across federated data sets within Netflix’s enterprise ecosystem. Although highly scalable and easy to configure, it still relies on a structured query language for input. Natural language based search has been possible for some time, but the level of effort required was high. The emergence of readily-available AI, specifically Large Language Models (LLMs), has created new opportunities to integrate AI search features, with a smaller investment and improved accuracy.

While Text-to-Query and Text-to-SQL are established problems, the complexity of distributed Graph Search data in the GraphQL ecosystem necessitates innovative solutions. This is the first in a three-part series where we will detail our journey: how we implemented these solutions, evaluated their performance, and ultimately evolved them into a self-managed platform.

The Need for Intuitive Search: Addressing Business and Product Demands

Natural language search is the ability to use everyday language to retrieve information as opposed to complex, structured query languages like the Graph Search Filter Domain Specific Language (DSL). When users interact with 100’s of various UIs within the suite of Content and Business Products applications, a frequent task is filtering a data table like the one below:

Example Content and Business Products application view

Ideally, a user simply wants to satisfy a query like “I want to see all movies from the 90s about robots from the US.” Because the underlying platform operates on the Graph Search Filter DSL, the application acts as an intermediary. Users input their requirements through UI elements — toggling facets or using query builders — and the system programmatically converts these interactions into a valid DSL query to filter the data.

The Complexity of filtering and DSL generation

This process presents a few issues.

Today, many applications have bespoke components for collecting user input — the experience varies across them and they have inconsistent support for the DSL. Users need to “learn” how to use each application to achieve their goals.

Additionally, some domains have hundreds of fields in an index that could be faceted or filtered by. A subject matter expert (SME) may know exactly what they want to accomplish, but be bottlenecked by the inefficient pace of filling out a large scale UI form and translating their questions in order to encode it in a representation Graph Search needs.

Most importantly, users think and operate using natural language, not technical constructs like query builders, components, or DSLs. By requiring them to switch contexts, we introduce friction that slows them down or even prevents their progress.

With readily-available AI components, our users can now interact with our systems through natural language. The challenge now is to make sure our offering, searching Netflix’s complex enterprise state with natural language, is an intuitive and trustworthy experience.

Natural language queries translated into Graph Search Filter DSL

We’ve made a decision to pursue generating Graph Search Filter statements from natural language to meet this need. Our intention is to augment and not replace existing applications with retrieval augmented generation (RAG), providing tooling and capabilities so that applications in our ecosystem have newly accessible means of processing and presenting their data in their distinct domain flavours. It should be noted that all the work here has direct application to building a RAG system on top of Graph Search in the future.

Under the Hood: Our Approach to Text-to-Query

The core function of the text-to-query process is converting a user’s (often ambiguous) natural language question into a structured query. We primarily achieve this through the use of an LLM.

Before we dive deeper, let’s quickly revisit the structure of Graph Search Filter DSL. Each Graph Search index is defined by a GraphQL query, made up of a collection of fields. Each field has a type e.g. boolean, string, and some have their permitted values governed by controlled vocabularies — a standardized and governed list of values (like an enumeration, or a foreign key). The names of those fields can be used to construct expressions using comparison (e.g. > or ==) or inclusion/exclusion operators (e.g. IN). In turn those expressions can be combined using logical operators (e.g. AND) to construct complex statements.

Graph Search Filter DSL

With that understanding, we can now more rigorously define the conversion process. We need the LLM to generate a Graph Search Filter DSL statement that is syntactically, semantically, and pragmatically correct.

Syntactic correctness is easy — does it parse? To be syntactically correct, the generated statement must be well formed i.e. follow the grammar of the Graph Search Filter DSL.

Semantic correctness adds some additional complexity as it requires more knowledge of the index itself. To be semantically correct:

  • it must respect the field types i.e. only use comparisons that make sense given the underlying type;
  • it must only use fields that are actually present in the index, i.e. does not hallucinate;
  • when the values of a field are constrained to a controlled vocabulary, any comparison must only use values from that controlled vocabulary.

Pragmatic correctness is much more difficult. It asks the question: does the generated filter actually capture the intent of the user’s query?

The following sections will detail how we pre-process the user’s question to create appropriate context for the instructions that we will provide to the LLM — both of which are fundamental to LLM interaction — as well as post-processing we perform on the generated statement to validate it, and help users understand and trust the results they receive.

At a high level that process looks like this:

Graph Search FIlter DSL generation process

Context Engineering

Preparation for the filter generation task is predominantly engineering the appropriate context. The LLM will need access to the fields of an index and their metadata in order to construct semantically correct filters. As the indices are defined by GraphQL queries, we can use the type information from the GraphQL schema to derive much of the required information. For some fields, there is additional information we can provide beyond what’s available in the schema as well, in particular permissible values that pull from controlled vocabularies.

Each field in the index is associated with metadata as seen below, and that metadata is provided as part of the context.

Graph Search index representation
  • The field is derived from the document path as characterized by the GraphQL query.
  • The description is the comment from the GraphQL schema for the field.
  • The type is derived from the GraphQL schema for the field e.g. Boolean, String, enum. We also support an additional controlled vocabulary type we will discuss more of shortly.
  • The valid values are derived from enum values for the enum type or from a controlled vocabulary as we will now discuss.

A controlled vocabulary is a specific field type that consists of a finite set of allowed values, which are defined by a SMEs or domain owners. Index fields can be associated with a particular controlled vocabulary, e.g. countries with members such as Spain and Thailand, and any usage of that field within a generated statement must refer to values from that vocabulary.

Naively providing all the metadata as context to the LLM worked for simple cases but did not scale. Some indices have hundreds of fields and some controlled vocabularies have thousands of valid values. Providing all of those, especially the controlled vocabulary values and their accompanying metadata, expands the context; this proportionally increases latency and decreases the correctness of generated filter statements. Not providing the values wasn’t an option as we needed to ground the LLMs generated statements- without them, the LLM would frequently hallucinate values that did not exist.

Curating the context to an appropriate subset was a problem we addressed using the well known RAG pattern.

Field RAG

As mentioned previously, some indices have hundreds of fields, however, most user’s questions typically refer only to a handful of them. If there was no cost in including them all, we would, but as mentioned prior, there is a cost in terms of the latency of query generation as well as the correctness of the generated query (e.g. needle-in-the-hackstack problem) and non-deterministic results.

To determine which subset of fields to include in the context, we “match” them against the intent of the user’s question.

  • Embeddings are created for index fields and their metadata (name, description, type) and are indexed in a vector store
  • At filter generation time, the user’s question is chunked with an overlapping strategy. For each chunk, we perform a vector search to identify the top K most relevant values and the fields to which they belong.
  • Deduplication: The top K fields from each chunk are both consolidated and deduplicated before being provided as context to the system instructions.
Field RAG process (chunking, merge, deduplicate)

Controlled Vocabularies RAG

Index fields of the controlled vocabulary type are associated with a particular controlled vocabulary, again, countries are one example. Given a user’s question, we can infer whether or not it refers to values of a particular controlled vocabulary. In turn, by knowing which controlled vocabulary values are present, we can identify additional, related index fields that should be included in the context that may not have been identified by the field RAG step.

Each controlled vocabulary value has:

  • a unique identifier within its type;
  • a human readable display name;
  • a description of the value;
  • also-known-as values or AKA display names, e.g. “romcom” for “Romantic Comedy”.

To determine which subset of values to include in the context for controlled vocabulary fields (and also possibly infer additional fields), we “match” them against the user’s question.

  • Embeddings are created for controlled vocabulary values and their metadata, and these are indexed in a vector store. The controlled vocabularies are available via GraphQL and are regularly fetched and reindexed so this system stays up to date with any changes in the domain.
  • At filter generation time, the user’s question is chunked. For each chunk, we perform a vector search to identify the top K most relevant values (but only for the controlled vocabularies that are associated with fields in the index)
  • The top K values from each chunk are deduplicated by their controlled vocabulary type. The associated field definition is then injected into the context along with the matched values.
Controlled Vocabularies RAG

Combining both approaches, the RAG of fields and controlled vocabularies, we end up with the solution that each input question resolves in available and matched fields and values:

Field and CV RAG

The quality of results generated by the RAG tool can be significantly enhanced by tuning its various parameters, or “levers.” These include strategies for reranking, chunking, and the selection of different embedding generation models. The careful and systematic evaluation of these factors will be the focus of the subsequent parts of this series.

The Instructions

Once the context is constructed, it is provided to the LLM with a set of instructions and the user’s question. The instructions can be summarised as follows: “Given a natural language question, generate a syntactically, semantically, and pragmatically correct filter statement given the availability of the following index fields and their metadata.”

  • In order to generate a syntactically correct filter statement, the instructions include the syntax rules of the DSL.
  • In order to generate a semantically correct filter statement, the instructions tell the LLM to ground the generated statement in the provided context.
  • In order to generate a pragmatically correct filter statement, so far we focus on better context engineering to ensure that only the most relevant fields and values are provided. We haven’t identified any instructions that make the LLM just “do better” at this aspect of the task.
Graph Search Filter DSL generation

After the filter statement is generated by the LLM, we deterministically validate it prior to returning the values to the user.

Validation

Syntactic Correctness

Syntactic correctness ensures the LLM output is a parsable filter statement. We utilize an Abstract Syntax Tree (AST) parser built for our custom DSL. If the generated string fails to parse into a valid AST, we know immediately that the query is malformed and there is a fundamental issue with the generation.

The other approach to solve this problem could be using the structured outputs modes provided by some LLMs. However, our initial evaluation yielded mixed results, as the custom DSL is not natively supported and requires further work.

Semantic Correctness

Despite careful context engineering using the RAG pattern, the LLM sometimes hallucinates both fields and available values in the generated filter statement. The most straightforward way of preventing this phenomenon is validating the generated filters against available index metadata. This approach does not impact the overall latency of the system, as we are already working with an AST of the filter statement, and the metadata is freely available from the context engineering stage.

DSL verification & hallucinations

If a hallucination is detected it can be returned as an error to a user, indicating the need to refine the query, or can be provided back to the LLM in the form of a feedback loop for self correction.

This increases the filter generation time, so should be used cautiously with a limited number of retries.

Building Confidence

You probably noticed we are not validating the generated filter for pragmatic correctness. That task is the hardest challenge: The filter parses (syntactic) and uses real fields (semantic), but is it what the user meant? When a user searches for “Dark”, do they mean the specific German sci-fi series Dark, or are they browsing for the mood category “dark TV shows”?

The gap between what a user intended and the generated filter statement is often caused by ambiguity. Ambiguity stems from the compression of natural language. A user says “German time-travel mystery with the missing boy and the cave” but the index contains discrete metadata fields like releaseYear, genreTags, and synopsisKeywords.

How do we ensure users aren’t inadvertently led to wrong answers or to answers for questions they didn’t ask?

Showing Our Work

One way we are handling ambiguity is by showing our work. We visualise the generated filters in the UI in a user-friendly way allowing them to very clearly see if the answer we’re returning is what they were looking for so they can trust the results..

We cannot show a raw DSL string (e.g., origin.country == ‘Germany’ AND genre.tags CONTAINS ‘Time Travel’ AND synopsisKeywords LIKE ‘*cave*’) to a non-technical user. Instead, we reflect its underlying AST into UI components.

After the LLM generates a filter statement, we parse it into an AST, and then map that AST to the existing “Chips” and “Facets” in our UI (see below). If the LLM generates a filter for origin.country == ‘Germany’, the user sees the “Country” dropdown pre-selected to “Germany.” This gives users immediate visual feedback and the ability to easily fine-tune the query using standard UI controls when the results need improvement or further experimentation.

Generated filters visualisation

Explicit Entity Selection

Another strategy we’ve developed to remove ambiguity happens at query time. We give users the ability to constrain their input to refer to known entities using “@mentions”. Similar to Slack, typing @ lets them search for entities directly from our specialized UI Graph Search component, giving them easy access to multiple controlled vocabularies (plus other identifying metadata like launch year) to feel confident they’re choosing the entity they intend.

If a user types, “When was @dark produced”, we explicitly know they are referring to the Series controlled vocabulary, allowing us to bypass the RAG inference step and hard-code that context, significantly increasing pragmatic correctness (and building user trust in the process).

Example @mentions usage in the UI

End-to-end architecture

As mentioned previously, the solution architecture is divided into pre-processing, filter statement generation, and then post-processing stages. The pre-processing handles context building and involves a RAG pattern for similarity search, while the post-processing validation stage checks the correctness of the LLM-generated filter statements and provides visibility into the results for end users. This design strategically balances LLM involvement with more deterministic strategies.

End-to-end architecture

The end-to-end process is as follows:

  1. A user’s natural language question (with optional `@mentions` statements) are provided as input, along with the Graph Search index context
  2. The context is scoped by using the RAG pattern on both fields and possible values
  3. The pre-processed context and the question are fed into the LLM with an instruction asking for a syntactically and semantically correct filter statement
  4. The generated filer statement DSL is verified and checked for hallucinations
  5. The final response contains the related AST in order to build “Chips” and “Facets”

Summary

By combining our existing Graph Search infrastructure with the power and flexibility of LLMs, we’ve bridged the gap between complex filter statements and user intent. We moved from requiring users to speak our language (DSL) to our systems understanding theirs.

The initial challenge for our users was successfully addressed. However, our next steps involve transforming this system into a comprehensive and expandable platform, rigorously evaluating its performance in a live production environment, and expanding its capabilities to support GraphQL-first user interfaces. These topics, and others, will be the focus of the subsequent installments in this series. Be sure to follow along!

You may have noticed that we have a lot more to do on this project, including named entity recognition and extraction, intent detection so we can route questions to the appropriate indices, and query rewriting among others. If this kind of work interests you, reach out! We’re hiring in our Warsaw office, check for open roles here.

Credits

Special thanks to Alejandro Quesada, Yevgeniya Li, Dmytro Kyrii, Razvan-Gabriel Gatea, Orif Milod, Michal Krol, Jeff Balis, Charles Zhao, Shilpa Motukuri, Shervine Amidi, Alex Borysov, Mike Azar, Bernardo Gomez Palacio, Haoyun He, Eduardo Ramirez, Cynthia Xie.


The AI Evolution of Graph Search at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Updated PCI PIN compliance package for AWS CloudHSM now available

Post Syndicated from Tushar Jain original https://aws.amazon.com/blogs/security/updated-pci-pin-compliance-package-for-aws-cloudhsm-now-available/

Amazon Web Services (AWS) is pleased to announce the successful completion of Payment Card Industry Personal Identification Number (PCI PIN) audit for the AWS CloudHSM service.

With CloudHSM, you can manage and access your keys on FIPS 140-3 Level 3 validated hardware, protected with customer-owned, single-tenant hardware security module (HSM) instances that run in your own virtual private cloud (VPC). This PCI PIN attestation gives you the flexibility to deploy your regulated workloads with reduced compliance overhead. CloudHSM might be suitable when operations supported by the service are integrated into a broader solution that requires PCI-PIN compliance. For payment operations, such as PIN translation, we encourage you to consider AWS Payment Cryptography as a fully managed alternative for PCI-PIN compliance.

The PCI PIN compliance report package for AWS CloudHSM includes two key components:

  • PCI PIN Attestation of Compliance (AOC) – demonstrating that AWS CloudHSM was successfully validated against the PCI PIN standard with zero findings
  • PCI PIN Responsibility Summary – provides guidance to help AWS customers understand their responsibilities in developing and operating a highly secure environment for handling PIN-based transactions

AWS was evaluated by Coalfire, a third-party Qualified Security Assessor (QSA). Customers can access the PCI PIN Attestation of Compliance (AOC) and PCI PIN Responsibility Summary reports through AWS Artifact.

To learn more about our PCI program and other compliance and security programs, see the AWS Compliance Programs page. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Tushar Jain

Tushar Jain

Tushar is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Tushar holds a Master of Business Administration from Indian Institute of Management Shillong, India and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 13 years of experience in information security and holds CCSK and CSXF certifications.

Will Black

Will Black

Will is a Compliance Program Manager at Amazon Web Services. He leads multiple security and compliance initiatives within AWS. He has ten years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he holds the CCSK and ISO 27001 Lead Implementer certifications.

The collective thoughts of the interwebz