Today, we are looking at the WD Black SN770M 1TB NVMe SSD. This is the third M.2 2230 sized SSD in my look at the current 2230 market; previous entries into this series are the Lexar PLAY and the Silicon Power UD90 2230. Just to review, the 2230 (30mm) sized drives are physically shorter than […]
Amazon OpenSearch Ingestion is a fully managed serverless pipeline that allows you to ingest, filter, transform, enrich, and route data to an Amazon OpenSearch Service domain or Amazon OpenSearch Serverless collection. OpenSearch Ingestion is capable of ingesting data from a wide variety of sources and has a rich ecosystem of built-in processors to take care of your most complex data transformation needs.
In this post, we walk you through the new UI enhancements and blueprint discovery features that are now available with OpenSearch Ingestion for a richer user experience.
Blueprint discovery
Rather than create a pipeline definition from scratch, you can use configuration blueprints, which are preconfigured templates for common ingestion scenarios such as trace analytics or Apache logs. Configuration blueprints help you provision pipelines without having to author a configuration from scratch.
With the older interface, you had to scroll through a dropdown menu of all the available blueprints and couldn’t filter the blueprints using search. OpenSearch Ingestion now offers a new UI that enables searching for blueprints using full-text search on the AWS Management Console, helping you discover all the sources that you can ingest data from into OpenSearch Service.
When you create a new pipeline on the OpenSearch Service console, you’re presented with a new catalog page. You now have a top-down view of all the sources and sinks supported by OpenSearch Ingestion. The blueprints are listed as tiles with icons and are grouped together thematically.
The new catalog has a navigation menu that lists the blueprints, grouped by use case or the service that you want to ingest data from. You can either search for a blueprint or choose the shortcuts in the navigation pane. For example, if you’re building a pipeline to perform a zero-ETL integration with Amazon DynamoDB, you can either search for DynamoDB, choose ZeroETL under Use case in the navigation pane, or choose DynamoDB under Service.
Customized getting started guide
After you choose your blueprint, you’re directed to the Pipeline settings and configuration page. The new UI for blueprints offers a customized getting started guide for each source, detailing key steps in setting up a successful end-to-end integration. The guide on this page will change depending on the blueprint you chose for your pipeline.
The pipeline configuration is pre-filled with a template that you can modify with your specific sources, AWS Identity and Access Management (IAM) roles, and sinks. For example, if you chose the Zero-ETL with DocumentDB blueprint, the getting started guide will provide information on setting up a DocumentDB collection, permissions, and destination.
Support for JSON pipeline configuration
As part of the visual overhaul, OpenSearch Ingestion now offers support for specifying the pipeline configuration in JSON format on the console in addition to the existing YAML support. You can now view the configurations in JSON format in addition to the YAML format and edit them in place.
Although YAML is more human readable, it’s whitespace sensitive and is often challenging when copy/pasting from text editors. The JSON pipeline configuration allows you to confidently copy and paste configurations from your text or code editors without having to worry about formatting errors due to inconsistent whitespace. In addition, you can now make any edits in place with JSON configuration and the changes will be propagated to the YAML automatically.
Availability and pricing
These features are available in all commercial AWS Regions where OpenSearch Ingestion is currently available.
Ingestion-OCUs remain at the same price of $0.24 cents per hour. OCUs are billed on an hourly basis with per-minute granularity. You can control the costs OCUs incur by configuring maximum OCUs that a pipeline is allowed to scale.
Conclusion
In this post, we showed you the new blueprint discovery and other UI enhancements for OpenSearch Ingestion. Refer to Amazon OpenSearch Ingestion to learn about other capabilities provided by OpenSearch Ingestion to build scalable pipelines for your OpenSearch data ingestion needs.
About the author
Jagadish Kumar (Jag) is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service. He is deeply passionate about Data Architecture and helps customers build analytics solutions at scale on AWS.
Sam Selvan is a Principal Specialist Solution Architect with Amazon OpenSearch Service.
In a
combined storage and filesystem session at the 2024 Linux Storage,
Filesystem, Memory Management, and BPF Summit, Luis Chamberlain led a
discussion on filesystem support for block sizes larger than the usual 4KB
page size,
which followed up on discussion from last year. While the
session was meant to look at the intersection of larger block sizes
with atomic block writes that avoid torn
(partial) writes (which was also discussed last year), it mostly focused on the
filesystem side. Over time, the
block sizes offered by storage devices have risen from the original
512 bytes; Chamberlain
wanted to discuss filesystem support for block sizes larger than 4KB.
Apache Hudi was originally developed by Uber in 2016 to bring to life a transactional data lake that could quickly and reliably absorb updates to support the massive growth of the company’s ride-sharing platform. Apache Hudi is now widely used to build very large-scale data lakes by many across the industry. Today, Hudi is the most active and high-performing open source data lakehouse project, known for fast incremental updates and a robust services layer.
Apache Hudi serves as an important data management tool because it allows you to bring full online transaction processing (OLTP) database functionality to data stored in your data lake. As a result, Hudi users can store massive amounts of data with the data scaling costs of a cloud object store, rather than the more expensive scaling costs of a data warehouse or database. It also provides data lineage, integration with leading access control and governance mechanisms, and incremental ingestion of data for near real-time performance. AWS, along with its partners in the open source community, has embraced Apache Hudi in several services, offering Hudi compatibility in Amazon EMR, Amazon Athena, Amazon Redshift, and more.
AWS Data Exchange is a service provided by AWS that enables you to find, subscribe to, and use third-party datasets in the AWS Cloud. A dataset in AWS Data Exchange is a collection of data that can be changed or updated over time. It also provides a platform through which a data producer can make their data available for consumption for subscribers.
In this post, we show how you can take advantage of the data sharing capabilities in AWS Data Exchange on top of Apache Hudi.
Benefits of AWS Data Exchange
AWS Data Exchange offers a series of benefits to both parties. For subscribers, it provides a convenient way to access and use third-party data without the need to build and maintain data delivery, entitlement, or billing technology. Subscribers can find and subscribe to thousands of products from qualified AWS Data Exchange providers and use them with AWS services. For providers, AWS Data Exchange offers a secure, transparent, and reliable channel to reach AWS customers. It eliminates the need to build and maintain data delivery, entitlement, and billing technology, allowing providers to focus on creating and managing their datasets.
To become a provider on AWS Data Exchange, there are a few steps to determine eligibility. Providers need to register to be a provider, make sure their data meets the legal eligibility requirements, and create datasets, revisions, and import assets. Providers can define public offers for their data products, including prices, durations, data subscription agreements, refund policies, and custom offers. The AWS Data Exchange API and AWS Data Exchange console can be used for managing datasets and assets.
Overall, AWS Data Exchange simplifies the process of data sharing in the AWS Cloud by providing a platform for customers to find and subscribe to third-party data, and for providers to publish and manage their data products. It offers benefits for both subscribers and providers by eliminating the need for complex data delivery and entitlement technology and providing a secure and reliable channel for data exchange.
Solution overview
Combining the scale and operational capabilities of Apache Hudi with the secure data sharing features of AWS Data Exchange enables you to maintain a single source of truth for your transactional data. Simultaneously, it enables automatic business value generation by allowing other stakeholders to use the insights that the data can provide. This post shows how to set up such a system in your AWS environment using Amazon Simple Storage Service (Amazon S3), Amazon EMR, Amazon Athena, and AWS Data Exchange. The following diagram illustrates the solution architecture.
Set up your environment for data sharing
You need to register as a data producer before you create datasets and list them in AWS Data Exchange as data products. Complete the following steps to register as a data provider:
Sign in to the AWS account that you want to use to list and manage products on AWS Data Exchange. As a provider, you are responsible for complying with these guidelines and the Terms and Conditions for AWS Marketplace Sellers and the AWS Customer Agreement. AWS may update these guidelines. AWS removes any product that breaches these guidelines and may suspend the provider from future use of the service. AWS Data Exchange may have some AWS Regional requirements; refer to Service endpoints for more information.
For Legal business name, enter the name that your customers see when subscribing to your data.
Review the terms and conditions and select I have read and agree to the AWS Marketplace Seller Terms and Conditions.
Select the information related to the types of products you will be creating as a data provider.
Choose Register & Sign into Management Portal.
If you want to submit paid products to AWS Marketplace or AWS Data Exchange, you must provide your tax and banking information. You can add this information on the Settings page:
Choose the Payment information tab.
Choose Complete tax information and complete the form.
Choose Complete banking information and complete the form.
Choose the Public profile tab and update your public profile.
Choose the Notifications tab and configure an additional email address to receive notifications.
You’re now ready to configure seamless data sharing with AWS Data Exchange.
Upload Apache Hudi datasets to AWS Data Exchange
After you create your Hudi datasets and register as a data provider, complete the following steps to create the datasets in AWS Data Exchange:
Sign in to the AWS account that you want to use to list and manage products on AWS Data Exchange.
On the AWS Data Exchange console, choose Owned data sets in the navigation pane.
Choose Create data set.
Select the dataset type you want to create (for this post, we select Amazon S3 data access).
Choose Choose Amazon S3 locations.
Choose the Amazon S3 location where you have your Hudi datasets.
After you add the Amazon S3 location to register in AWS Data Exchange, a bucket policy is generated.
Copy the JSON file and update the bucket policy in Amazon S3.
After you update the bucket policy, choose Next.
Wait for the CREATE_S3_DATA_ACCESS_FROM_S3_BUCKET job to show as Completed, then choose Finalize data set.
Publish a product using the registered Hudi dataset
Complete the following steps to publish a product using the Hudi dataset:
On the AWS Data Exchange console, choose Products in the navigation pane. Make sure you’re in the Region where you want to create the product.
Choose Publish new product to start the workflow to create a new product.
Choose which product visibility you want to have: public (it will be publicly available in AWS Data Exchange catalog as well as the AWS Marketplace websites) or private (only the AWS accounts you share with will have access to it).
Select the sensitive information category of the data you are publishing.
Choose Next.
Select the dataset that you want to add to the product, then choose Add selected to add the dataset to the new product.
Define access to your dataset revisions based on time. For more information, see Revision access rules.
Choose Next.
Provide the information for a new product, including a short description. One of the required fields is the product logo, which must be in a supported image format (PNG, JPG, or JPEG) and the file size must be 100 KB or less.
Optionally, in the Define product section, under Data dictionaries and samples, select a dataset and choose Edit to upload a data dictionary to the product.
For Long description, enter the description to display to your customers when they look at your product. Markdown formatting is supported.
Choose Next.
Based on your choice of product visibility, configure the offer, renewal, and data subscription agreement.
Choose Next.
Review all the products and offer information, then choose Publish to create the new private product.
Manage permissions and access controls for shared datasets
Datasets that are published on AWS Data Exchange can only be used when customers are subscribed to the products. Complete the following steps to subscribe to the data:
On the AWS Data Exchange console, choose Browse catalog in the navigation pane.
In the search bar, enter the name of the product you want to subscribe to and press Enter.
Choose the product to view its detail page.
On the product detail page, choose Continue to Subscribe.
Choose your preferred price and duration combination, choose whether to enable auto-renewal for the subscription, and review the offer details, including the data subscription agreement (DSA). The dataset is available in the US East (N. Virginia) Region.
Review the pricing information, choose the pricing offer and, if you and your organization agree to the DSA, pricing, and support information, choose Subscribe.
After the subscription has gone through, you will be able to see the product on the Subscriptions page.
Create a table in Athena using an Amazon S3 access point
Complete the following steps to create a table in Athena:
Open the Athena console.
If this is the first time using Athena, choose Explore Query Editor and set up the S3 bucket where query results will be written: Athena will display the results of your query on the Athena console, or send them through your ODBC/JDBC driver if that is what you are using. Additionally, the results are written to the result S3 bucket.
Choose View settings.
Choose Manage.
Under Query result location and encryption, choose Browse Amazon S3 to choose the location where query results will be written.
Choose Save.
Choose a bucket and folder you want to automatically write the query results to. Athena will display the results of your query on the Athena console, or send them through your ODBC/JDBC driver if that is what you are using. Additionally, the results are written to the result S3 bucket.
Complete the following steps to create a workgroup:
In the navigation pane, choose Workgroups.
Choose Create workgroup.
Enter a name for your workgroup (for this post, data_exchange), select your analytics engine (Athena SQL), and select Turn on queries on requester pay buckets in Amazon S3. This is important to access third-party datasets.
In the Athena query editor, choose the workgroup you created.
Run the following DDL to create the table:
Now you can run your analytical queries using Athena SQL statements. The following screenshot shows an example of the query results.
Enhanced customer collaboration and experience with AWS Data Exchange and Apache Hudi
AWS Data Exchange provides a secure and simple interface to access high-quality data. By providing access to over 3,500 datasets, you can use leading high-quality data in your analytics and data science. Additionally, the ability to add Hudi datasets as shown in this post allows you to enable deeper integration with lakehouse use cases. There are several potential use cases where having Apache Hudi datasets integrated into AWS Data Exchange can accelerate business outcomes, such as the following:
Near real-time updated datasets – One of Apache Hudi’s defining features is the ability to provide near real-time incremental data processing. As new data flows in, Hudi allows that data to be ingested in real time, providing a central source of up-to-date truth. AWS Data Exchange supports dynamically updated datasets, which can keep up with these incremental updates. For downstream customers that rely on the most up-to-date information for their use cases, the combination of Apache Hudi and AWS Data Exchange means that they can subscribe to a dataset in AWS Data Exchange and know that they’re getting incrementally updated data.
Incremental pipelines and processing – Hudi supports incremental processing and updates to data in the data lake. This is especially valuable because it enables you to only update or process any data that has changed and materialized views that are valuable for your business use case.
Best practices and recommendations
We recommend the following best practices for security and compliance:
Enable AWS Lake Formation or other data governance systems as part of creating the source data lake
To maintain compliance, you can use the guides provided by AWS Artifact
For monitoring and management, you can enable Amazon CloudWatch logs on your EMR clusters along with CloudWatch alerts to maintain pipeline health.
Conclusion
Apache Hudi enables you to bring to life massive amounts of data stored in Amazon S3 for analytics. It provides full OLAP capabilities, enables incremental processing and querying, along with maintaining the ability to run deletes to remain GDPR compliant. Combining this with the secure, reliable, and user-friendly data sharing capabilities of AWS Data Exchange means that the business value unlocked by a Hudi lakehouse doesn’t need to remain limited to the producer that generates this data.
Saurabh Bhutyani is a Principal Analytics Specialist Solutions Architect at AWS. He is passionate about new technologies. He joined AWS in 2019 and works with customers to provide architectural guidance for running generative AI use cases, scalable analytics solutions and data mesh architectures using AWS services like Amazon Bedrock, Amazon SageMaker, Amazon EMR, Amazon Athena, AWS Glue, AWS Lake Formation, and Amazon DataZone.
Ankith Ede is a Data & Machine Learning Engineer at Amazon Web Services, based in New York City. He has years of experience building Machine Learning, Artificial Intelligence, and Analytics based solutions for large enterprise clients across various industries. He is passionate about helping customers build scalable and secure cloud based solutions at the cutting edge of technology innovation.
Chandra Krishnan is a Solutions Engineer at Onehouse, based in New York City. He works on helping Onehouse customers build business value from their data lakehouse deployments and enjoys solving exciting challenges on behalf of his customers. Prior to Onehouse, Chandra worked at AWS as a Data and ML Engineer, helping large enterprise clients build cutting edge systems to drive innovation in their organizations.
The term “memory model” is used in a couple of ways within the kernel.
Perhaps the more obscure meaning is the memory-management subsystem’s view
of how physical memory is organized on a given system. A proper
representation of physical memory will be more efficient in terms of memory
and CPU use. Since hardware comes in numerous variations, the kernel
supports a number of memory models to match; see this article for details. At the 2024 Linux Storage,
Filesystem, Memory-Management and BPF Summit, Oscar Salvador,
presenting remotely, made the case for removing one of those models.
Въпреки продължаващите седмици масови протести, парламентът в Грузия окончателно прие оспорвания закон за „чуждите агенти“.
„Всички мои познати и роднини са на протеста, защото разбират, че този закон е също като руския и ще доведе до репресии. Всъщност веднага щом го приеха, властта в Грузия показа истинското си проруско лице и репресиите започнаха. Полицията арестува протестиращи без всякаква причина,бие и малтретира невинни хора, които са излезли да изкажат мнението си на площада – същото, което прави и полицията в Русия при всеки протест там. Поведението на грузинската полиция днес е същото като на руската. А законът е току-що приет. Представете си.“
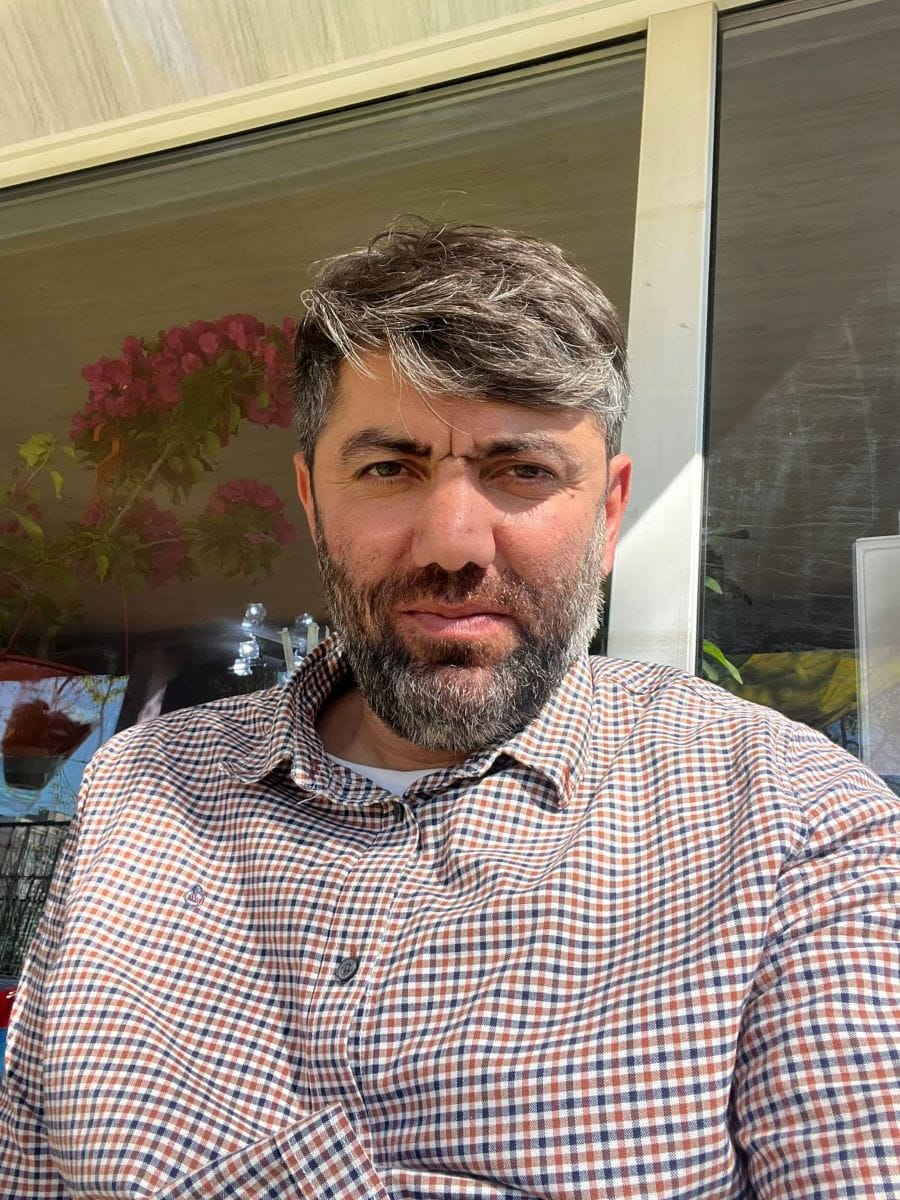
Така започна разговорът ми с грузинеца Серго Маркарян. Гласът му идва през приложението на телефона бодър и оптимистичен. Не ме изчаква да го попитам нещо. Говори бързо и убедено.
„Властта няма да може да се справи с тези протести. В момента в Грузия затварят училища и университети, за да излязат да протестират срещу тази власт. Преподавателите, студентите, учениците – всички излизат. Скоро и шофьорите от градския транспорт ще спрат работа и ще са на протеста. Хората няма да се откажат. Това е сигурно. Политиците ще клекнат, защото ще видят, че никой не иска да работи за тях и да ги обслужва. Ще видят, че университетите и училищата са затворени. Няма къде да ходят. Ще клекнат пред протеста. Няма власт, която да устои на това. Ще избягат, защото няма да имат друг изход. Никаква полиция няма да може да спре протестите.“
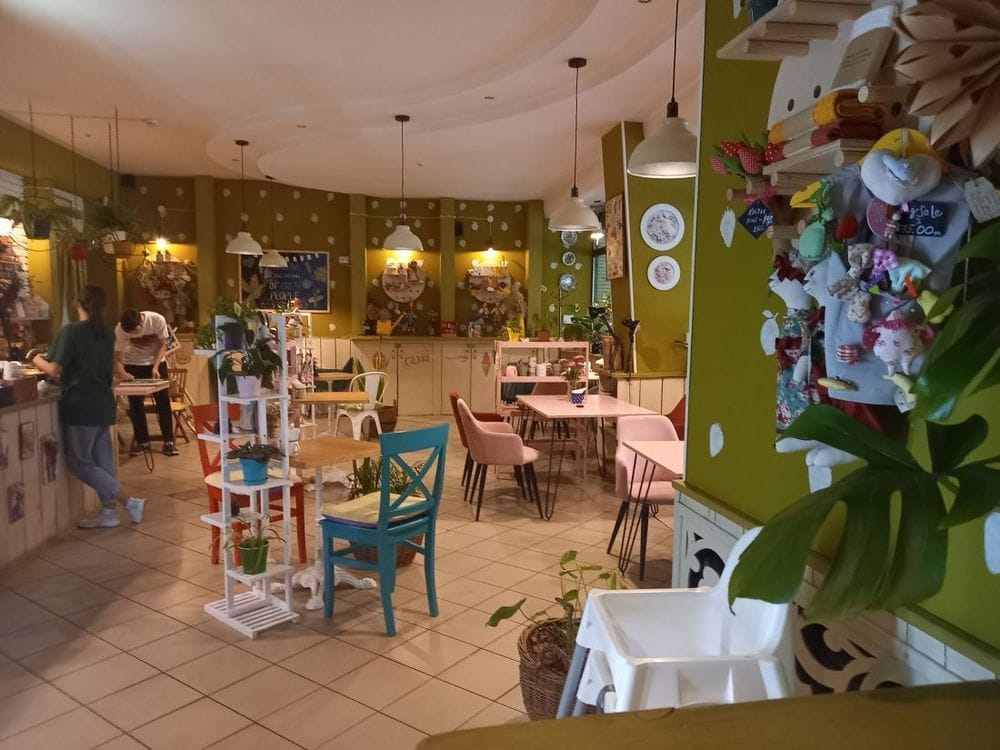
Серго е грузинец, който живее в Украйна, но всичките му роднини са в Грузия. Той има малка сладкарничка насред Буча,
където след нахлуването на Русия в Украйна бяха извършени едни от най-жестоките издевателства над украински граждани. По това време Серго с личния си автомобил спасява много хора от руските войски, разнася хуманитарна помощ на затворените в мазета и убежища украинци, за да не умрат от глад. Руснаците стрелят по него, но както той казва,
имах късмет, мой приятел нямаше този късмет и го убиха до мен.
Срещнах Серго преди почти година при посещението ми в Украйна. Тогава той ми показа видеото със стрелбата по колата му, докато я е карал, показа ми и видео с разрушеното от руските войски кафене. Спомням си ясно как тогава насред китната му сладкарничка попитах дали държавата му е помогнала да възстанови кафенето си след края на окупацията. Той свенливо се засмя и ми отговори: „Не, ние със съпругата ми полека-лека възстановихме всичко сами. Има по-нуждаещи се от нас в Украйна и нека държавната помощ отиде за тях.“
Тогава със Серго говорихме надълго и нашироко за руската пропаганда. Докато той ми разказваше как полицията бие протестиращите грузинци, се сетих за публикации в български сайтове, където се появи следната теза: „Протестите изобщо не са всенародни. Протестират активисти на НПО сектора, които от години живеят на издръжката на евроатлантическите си донори.“
Казах това на грузинския ми познат. Той замълча за миг. Представих си го – висок, едър мъж с широка усмивка и светнали очи. Плътният му глас буквално загърмя в слушалката:
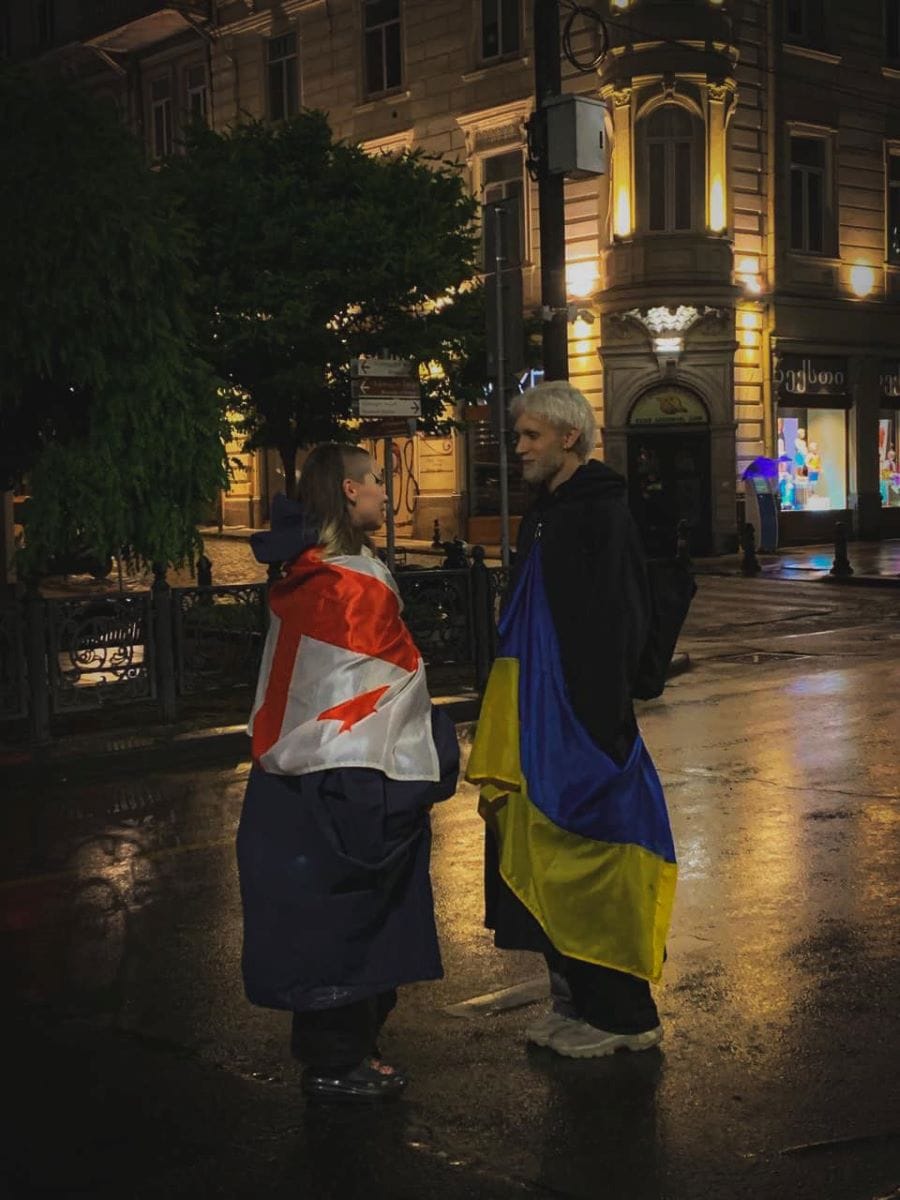
„Това е 100% невярно, защото на протестите излизат дори децата на депутатите, приели този закон. Младите хора вече знаят какво е диктатура, ясен им е руският стил на управление, разбират и какво означава политиците да са продажни. В Тбилиси живеят около един милион души. На последния протест излязоха около 270–280 000 човека заедно с децата си на по 10, 12, 15 години. Това е рекорд за Грузия, никога не е имало такава гражданска активност. Хората ги обединява мисълта, че някой иска да ги приобщи към Русия. На всички трябва да е ясно, че над 80% от населението на Грузия категорично са против Русия. Не просто против или колебаещи се, а категорично против Русия. За мен обаче големият въпрос е откъде накъде Русия има толкова голямо влияние в България, въпреки че сте част от ЕС. На този въпрос не мога да си отговоря.
Добре че НАТО ви пази, защото не мога да си представя какво би се случило с вас, ако не бяхте член на НАТО.“
Този път беше мой ред да замълча. За миг си помислих какво ли би станало в България, ако в нашия парламент бъде приет законът за „чуждестранните агенти“ на партия „Възраждане“, който толкова прилича на този в Грузия и на руския. Колко ли български граждани щяха да разберат опасността от такъв закон и щяха да излязат да протестират.
Измъквам се от мислите си с реплика към Серго, че не е учудващо приемането на този закон, защото все пак Грузия стои доста близо до Русия в икономически план, а и в отношението на грузинското правителство към войната в Украйна.
„Да, защото управляващите ни са проруски. Всъщностнашите политици показаха истинското си лице, когато започна войната в Украйна. До този момент те не показваха откровената си проруска позиция. Но щом започна войната, заеха страна против Украйна. Започнаха да я обвиняват, че тя е виновна за войната, че не я е предотвратила, а е можела. Те никога не поставиха акцента, че Русия започна войната и нападна Украйна, за да я унищожи като демократично общество, което се стреми към свобода. Но гражданите на Грузия не искат да бъдат роби, точно както и украинските. Днес се решава с кого ще бъде Грузия занапред – с Европа или с Русия. Ако избере Русия, това ще е нашият край. Просто ще станем като Беларус.
Всяка държава, която е попаднала под въздействието на Русия и под нейната власт, се превръща в диктатура и става подобна на Беларус.“
Питам Серго на какво според него се дължат тази категоричност и негативното отношение на грузинското общество към Русия. Серго прави отново кратка пауза. Обичайно силният му весел глас помръква.
„Грузинците имат причина да бъдат срещу Русия.Русия години наред е издевателствала над грузинския народ. Руснаците са изнасилвали нашите жени и деца, отвличали са деца, убивали са народа ни точно както го правят сега в Украйна, и никой няма да им прости това. Ако германците се извиниха за издевателствата над еврейския народ по време на Втората световна война, то руснаците никога не се извиниха на грузинците за зверствата, които са ни причинили. Напротив – те не само не се извиниха, а говорят, че са прави за всичко, което са ни сторили. Така че никога не можем да им простим. Винаги са искали да ни поставят на колене и да ни направят свои роби, а ние сме се съпротивлявали. И тъкмо успяхме поне малко да се откачим от тях – ето, дойде този закон. Това са просто някакви зверове, с които не може да имаш нищо общо.“
Напомням на Серго, че миналата година имаше опит същият този закон да бъде приет, но тогава депутатите в грузинския парламент се отказаха. Защо го приеха тъкмо сега?
„Тогава видяха, че народът се обединява срещу тях, и решиха, че трябва да изчакат. Използваха тази половин година, за да развият своите проруски канали. Месеци наред разказваха как в този закон няма нищо страшно, че неправителствените организации са наистина реални чуждестранни агенти и застрашават суверенитета на Грузия, че ЕС е нещо лошо, а Америка иска да ни скара с Русия и да влезем във война с нея. Близо година говореха такива глупости по всякакви канали.“
Според Серго преди по-малко от година, при предишните протести, около 15% от населението на Грузия е било настроено проруски и е подкрепяло закона за „чуждестранните агенти“. След „масираната пропаганда“ от страна на правителството на негова страна са спечелени може би още около 5%.
„Това беше хитър ход на властта. Мислеха си, че като си дадат време преди втория опит да приемат закона, ще успеят да спечелят много повече граждани на тяхна страна. Е, излъгаха се, защото към този момент 80% от населението не се хвана на техните уловки и е против близостта ни с Русия и против този закон конкретно. Сега на нашия Иванишвили ще му се наложи да каже ясно на чия страна е – на страната на Русия или на Европа. Разбирате ли, Русия винаги напада и превзема държави, където има такива политици като нашия Иванишвили или като унгарския Орбан и където пропагандата ѝ успява да проникне сред обществото.“
Тезата на Серго ми се струва убедителна, но сякаш има и още нещо. Поне така си мисля оттук. Споделям с него, че може би увереността на грузинските политици се дължи и на това, че Западът забави помощта си за Украйна толкова много и това е дало повод както на Русия, така и на проруските политици в Грузия да опитат със закона отново, защото са усетили слабост и колебание.
„Всеки сблъсък с Русия е равен на катастрофа и се надявам, че светът се готви за тази катастрофа, защото тя засега изглежда неизбежна.
Дано цивилизованият свят разбира, че ако Украйна загуби войната и руснаците ни превземат, те ще ни задължат да се сражаваме срещу вас, срещу цивилизования свят. Знам, че това звучи странно, но погледнете какво се случва в окупираните украински територии – там вече започна мобилизация на местното население, което ще бъде изпратено съвсем скоро да воюва срещу украинци. Ще изправят един срещу друг украинци. По същия начин биха изправили и украинци срещу Европа. Що се отнася до забавената помощ за Украйна, знаете ли, аз винаги съм вярвал, че ние сме си виновни сами за нещата, които ни се случват. Никакъв Запад не ни е виновен.
Ако в България има проруска власт, значи вие сте си избрали тази власт, ако в Грузия имаме проруска власт, значи ние сме си я избрали.
Ако в Украйна президент беше Янукович, значи него сме си избрали. Никакъв Запад не е отговорен за нашите действия. Това, което Европа със сигурност прави, е, че като вижда как руснаците искат напълно да ни унищожат, направо да ни изтрият от земята (говоря за украинците), тя се опитва да ни помогне с хуманитарна и каквато друга помощ може. Всичко останало си е наша грижа и ние трябва да се справим със случващото се. Това по някакъв начин е наказание за нашите граждански действия или бездействия. За Грузия важи същото. Явно тези, които разбираме какво се случва с руската пропаганда, разбираме каква е Русия, не сме успели да обясним на останалите каква опасност ни грози всички заедно.
Искаме демокрация и по тази причина Русия се опитва да ни унищожи,
това не сме успели да обясним добре. Явно едва когато успеем да узреем всички ние – гражданите и политиците на Грузия, Украйна, дори България, когато съумеем да докажем, че сме готови и заслужили да бъдем част от демократичния свят, едва тогава можем да искаме от този свят да ни защитава.“
Изведнъж Серго млъкна. Бях като зашеметена от казаното от него. Очаквах всичко друго, но не и това, което уверено ми говореше току-що. Паузата стана толкова дълга, че когато отново чух гласа му, той колебливо ме попита дали връзката не е прекъснала. Отвърнах, че съм на линия, но мисля върху думите му. Тогава Серго продължи така:
„Аз имам само един въпрос по отношение на Русия. Ако Русия има свободата да унищожава произволна нация, да убива и насилва хората ѝ, то това е хаос и някой трябва да я спре. Защото не е редно да се случва такова нещо. Ако някой убива, той трябва да бъде наказан. Ако аз убия някого, трябва да отида в затвора, нали, а не да ме попитат дали някога ще убивам пак, и доверчиво да ме пуснат. Защото аз, естествено, ще обещая да не правя така повече, а щом ме пуснат безнаказано, отново ще убия.
Та аз питам: кой трябва да бъде съдия на Русия?
Да допуснем, че Украйна не се справи, а нас всички ни избият тук. Аз питам: има ли кой да накаже Русия за стореното? Някой може ли да ми отговори на този въпрос?“
След всичко казано от Серго сякаш ми остана само да го попитам какво според него ще се случи в Грузия. Гласът му отново долетя до мен силен и с далечна усмивка.
„В момента нашите политици ни плашат с война и ни казват: слушайте ни, нали не искате война?! Да, ние грузинците не искаме война, но не искаме и да сме роби на Русия. Ние искаме да сме свободни и ако не сме свободни, по-добре да не сме живи.Това казват днес протестиращите на грузинското правителство. Какво ще стане с Грузия ли? Според мен ще успеем да свалим тази власт. Няма да е лесно, но те са страхливи. Много хора са на площадите. Аз също тръгвам след няколко дни към Грузия, защото го чувствам като свой граждански дълг – да съм там, сред народа си, и да го подкрепям.“
For every page of memory in the system, the kernel maintains a set of page
flags describing how the page is used and various aspects of its current
state. Space for page flags has been in chronic short supply, leading to a desire to
eliminate or consolidate them whenever possible. That objective, though,
is hampered by the fact that the purpose of many page flags is not well
understood. In a memory-management-track session at the 2024 Linux Storage,
Filesystem, Memory-Management and BPF Summit, Matthew Wilcox set out to
cooperatively update the page-flag documentation to improve that situation.
The problem of sharing page tables across processes has been discussed
numerous times over the years, Khaled Aziz said at the beginning of his 2024 Linux Storage,
Filesystem, Memory-Management and BPF Summit session on the topic. He
was there to, once again, talk about the proposed mshare() system call (which, in its
current form, is no longer actually a system call but the feature still
goes by that name) and to see what can be done to finally get it into the
mainline.
The kernel’s hugetlbfs
subsystem was the first mechanism by which the kernel made huge pages
available to user space; it was added to the 2.5.46 development kernel in
2002. While hugetlbfs remains useful, it is also viewed as a sort of
second memory-management subsystem that would be best unified with the rest
of the kernel. At the 2024 Linux Storage,
Filesystem, Memory-Management and BPF Summit, Peter Xu raised the
question of what that unification would involve and what the first steps
might be.
KeePassXC is an open-source (GPLv3),
cross-platform password manager with local-only data storage. The
project comes with a number of build
options that can be used to toggle optional features, such as browser
integration and password
database sharing. However, controversy ensued when Debian Developer Julian Klode decided to
make use of these compile flags to disable these features to improve security in the keepassxc package uploaded to Debian unstable for the
upcoming Debian 13 (“Trixie”) release.
The 2024 Linux
Storage, Filesystem, Memory-Management and BPF Summit was a development
conference, where discussion was prioritized and presentations with a lot
of slides were discouraged. Paul McKenney seemingly flouted this
convention in a joint session of the storage, filesystem, and
memory-management tracks where he presented about 50 slides — in five
minutes, twice. The subject was the use of the read-copy-update (RCU)
mechanism in the memory-reclaim process, and whether changes to RCU would
be needed for that purpose.
Amazon Simple Email Service (SES) is a cloud-based email sending service provided by Amazon Web Services (AWS), handling both inbound and outbound email traffic for your applications. It allows users to send and receive email using SES’s reliable and cost-effective infrastructure without having to provision email servers yourself.
Managing multiple email workloads at scale can be a daunting task for organizations. From handling high volumes of emails to routing them efficiently, and ensuring uniform compliance with regulations, the challenges can be overwhelming. Managing different types of outbound emails, whether one-to-one user email, transactional or marketing emails generated from applications, also becomes challenging due to increasing concerns of security and compliance requirements. To help customers tackle these pain points, Amazon Web Services (AWS) has introduced a new feature to streamline inbound and outbound email management: SES Mail Manager.
The challenge: Managing different email flows efficiently with compliance and security in place
Efficiently routing and processing emails to the appropriate teams or systems while ensuring proper filtering, security, and compliance is a complex undertaking. Meanwhile, outbound email flows have become increasing complex. Besides emails being sent between users, more and more emails are generated from different types of applications. On top of that, keeping up security and compliance requirements is an ongoing task for all IT administrators and CISOs. Maintaining email integrations with existing business applications, providing scalability and redundancy to accommodate spikes, and facilitating long-term archiving and retrieval further compound the difficulties. Without a robust and scalable solution, organizations struggle to manage email communications effectively, hindering productivity and exposing themselves to risks.
Solution: Amazon SES Mail Manager
Amazon SES Mail Manager is a comprehensive solution with powerful set of email gateway features that strengthens your organization’s email infrastructure. It simplifies email workflow management and streamlines compliance control, while integrating seamlessly with your existing systems. Mail Manager consolidates all incoming and outgoing email through a single control point. This allows you to apply unified tools, rules, and delivery behaviors across your entire email flow. The centralized approach improves reliability, security, and flexibility.
Some key capabilities include connecting different business applications, automating inbound email processing, managing outgoing emails, enhancing compliance through email archiving, and efficiently controlling overall email traffic. It provides a centralized hub to optimize email infrastructure, simplify processes, ensure compliance, and maintain a high degree of reliability and security.
Mail Manager features
Ingress Endpoints: Customizable SMTP endpoints for receiving emails
Ingress endpoint is a key infrastructure component that utilizes filtering polices and rules that you can configure to determine which emails should be allowed into your organization and which ones should be rejected.
Amazon SES currently offers a way to receive incoming emails from the internet using its SMTP interface called SES Inbound. This provided a shared, regional SMTP endpoint that all SES customers could use to accept emails. Improved upon this, Mail Manager introduces a more flexible and powerful approach with different types of ingress endpoints to handling inbound email with Amazon SES.
Mail Manager now offers two options for customers: Open Ingress Endpoint, Authenticated Ingress Endpoint.
Open Ingress Endpoints allows you to create unique, customizable SMTP endpoints that give you control to accept or reject email messages tailored to your specific needs. Open Ingress Points do not require domain verification to receive inbound emails. Simply point your domain’s MX record to the newly created Ingress Endpoint, and it will start receiving emails for that domain.
Authenticated Ingress Endpoints in Mail Manager also enables a new capability – allowing SES to accept emails from trusted external SMTP servers for further processing. Users can create a Traffic Policy to configure trusted external SMTP servers with either type of Ingress Endpoints. What’s different about Authenticated Ingress Endpoints is, users need to use SMTP Authorization to send messages. Once provisioned, you obtain credentials to connect your existing email infrastructure to the Authenticated Ingress Endpoint as an outgoing email server.
For step-by-step guide on how to create this, refer to documentation.
Traffic policies & policy statements
Traffic Policies enable fine-grained control over accepting or rejecting inbound email. A traffic policy is a container for policy statements that you assign to an ingress endpoint, so that it can sort the incoming mail by allowing or blocking specific types of email when the conditions of the policy statements are met. You have the option to set a maximum message size so that any email with a size greater, will immediately be discarded—this acts as a “first pass” filter when set. Next, you set either Allow or Deny as the default action that’s taken for email that falls outside of the conditions of your policy statements. This is the “catch all” action for the traffic policy.
Policy statements are also created with either an allow or block action that is taken when the statements’ conditions are met. You build the conditions by selecting an email protocol and a conditional operator for a value you enter that must be matched by the incoming message before the policy statement will allow or block it. The three conditions available in the policy statement are Recipient address, Sender IP range and TLS protocol version. Each policy statement can have multiple conditions.
Rule Sets & rules
Taking Control with Rule Sets: After traffic policies permit certain messages into Mail Manager, customers use rule sets to apply custom processing logic for routing, optional functions, archiving, and delivery. You can add multiple Rules within a Rule Set. You can specify the order in which Rules within a Rule Set are evaluated, as well as the order of Actions within each Rule. Each Rule consists of: Conditions: Criteria that an email must match for the Rule to be applied. Exceptions: Criteria that, if matched, will exempt the email from the Rule. Actions: The operations to be performed on emails that meet the Rule’s Conditions and don’t match any Exceptions.
Recipient-Oriented Processing:
Mail Manager processes emails in a recipient-oriented manner, meaning rules are applied separately for each recipient. In traditional email gateways, rules are typically applied at the message level, affecting all recipients uniformly. For instance, if a rule in a traditional gateway adds a header for emails addressed to [email protected], all recipients of that email will see the header. This can lead to unintended side effects where actions meant for one recipient affect others. With Mail Manager, only emails to [email protected] will have the header, ensuring rules are specific to each recipient.
Additionally, Mail Manager allows rules to be applied to all recipients when needed, such as using the Subject header as a rule condition. This flexibility provides greater precision and control in email processing, allowing rules administrators to tailor the application of rules to meet specific requirements for individual recipients or for the entire email.
By enabling both recipient-oriented and message-oriented approaches, it enhances privacy, compliance, and security by preventing unintended data exposure and ensuring actions are applied only where intended.
Flexible Conditions and Actions: Mail Manager’s Rule Sets offer a powerful expression language for defining conditions based on various email properties, such as recipient address, TLS version, source IP, subject header, and more. Additionally, Rule Sets support a wide range of Actions, including:
With these capabilities, Rule Sets enable you to build sophisticated, automated email processing workflows tailored to your organization’s needs.
SMTP Relay
Mail Manager’s SMTP Relay functionality allows you to integrate your inbound email processing workflows with external email infrastructure, such as on-premises Microsoft Exchange servers or third-party email gateways. Mail Manager’s SMTP Relay functionality allows you to integrate your email flows with appropriate servers based on predefined criteria, optimizing the journey of every email.
How SMTP Relay Works:
Define an SMTP Relay – First, you create an SMTP Relay resource within Mail Manager, specifying the details of the external SMTP server you want to relay emails to, such as the server hostname, port, and authentication credentials (if required).
Create a Rule with the SMTP Relay Action Next, within a Rule Set, you create a Rule that includes the “SMTP Relay” action, selecting the SMTP Relay resource you defined earlier.
Configure the Rule Conditions You then set the conditions for this Rule, determining which incoming emails should be relayed to the external SMTP server. For example, you could set a condition to relay all email destined for a specific domain (e.g., “@gmail.com”).
Assign the Rule Set to an Ingress Endpoint Finally, you assign the Rule Set containing this Rule to one or more Ingress Endpoints.
When an email matching the Rule’s conditions is received by the Ingress Endpoint, Mail Manager will automatically relay that email to the external SMTP server specified in the SMTP Relay resource.
Use Cases for SMTP Relay:
Processing layer for incoming emails: Relay incoming emails from Mail Manager after rules engine processing to your email server whether it’s on-premises or cloud email system.
Supporting hybrid and migration: In hybrid email environments where some mailboxes are hosted on-premises and others are in the cloud (e.g., Microsoft 365 or Google Workspace), SMTP relay allows for seamless communication between the two environments. During email migration projects, SMTP relay can be used to temporarily route emails between the old and new email platforms, ensuring that no messages are lost during the transition period.
Mailbox resilience: By terminating MX at Mail Manager, and then configuring rules for delivery to 1 or more mailbox providers, you can manage resilient mailbox delivery if your primary mailbox provider is impaired. No DNS propagation delays, just change the delivery rule and instantly fall into your other system.
Enforcement layer: Integrate Mail Manager with third-party email services or gateways by relaying emails to their SMTP endpoints, leveraging their capabilities to enforce additional policies or security measures while maintaining control with Mail Manager.
Inter-Server Communication: SMTP relay facilitates communication between different internal email servers or systems within the organization’s network, ensuring seamless delivery of emails across various domains or platforms.
Load balancing and redundancy: Distribute email traffic across multiple servers or gateways to optimize performance and resource utilization, ensuring high availability and fault tolerance.
With SMTP Relay, Mail Manager acts as a flexible email processing layer, allowing you to incorporate its powerful capabilities while maintaining and extending your current email infrastructure investments.
Email Archiving
As organizations face increasing regulatory and compliance requirements around email retention, Mail Manager provides a robust email archiving solution. The archiving feature allows you to securely store and easily search through your email data, ensuring you meet your archiving obligations.
How Email Archiving Works:
You create an archive resource within Mail Manager, specifying the desired retention period for your archived emails.
Create a Rule with the archive action within a Rule Set. Create a Rule that includes the “Archive” action, selecting the Archive resource you defined earlier.
You then set the conditions for this Rule, determining which incoming emails should be archived. For example, you could archive all emails sent to a specific department’s email alias.
Finally, you assign the Rule Set containing this archiving Rule to one or more Ingress Endpoints.
Now, when an email matching the Rule’s conditions is received by the Ingress Endpoint, Mail Manager will automatically archive a verbatim copy of that email to the designated Archive resource.
Mail Manager’s archiving capabilities offer several advantages for organizations:
Archiving stores email data in a secure, durable, and searchable archive, meeting regulatory requirements for email retention and enabling efficient audits.
Utilize powerful search filters to locate specific emails within your archive, and export search results for further analysis or legal purposes.
Reduce the storage burden on your mail servers by archiving emails to Mail Manager’s scalable and cost-effective storage solution.
Set customizable retention periods for your archives, ensuring important email data is preserved for as long as needed.
By integrating email archiving into your Mail Manager workflows, you can maintain a comprehensive, searchable, and compliant email archive without the hassle of managing additional infrastructure.
Email Add-ons
Mail Manager offers a suite of specialized security tools, called Email Add-ons, that allow you to enhance your email security posture and tailor your inbound email workflows to your specific needs. Add-ons can be used as conditions within Traffic Policies to control which emails are allowed into your Ingress Endpoints, or as conditions within Rule Sets to determine the actions taken on specific email types. These Add-ons are certified security intelligence and enforcement solutions from vetted providers, ready to be integrated directly into your Mail Manager environment (e.g., Spamhaus Domain Block List, Abusix Mail Intelligence, Trend Micro Virus Scanning).
Email Add-Ons provide a flexible and modular approach to email security, enabling you to select and combine the solutions that best fit your unique use cases. Instead of investing in a monolithic product that may not fully align with your requirements, you can choose from a range of Add-ons and pay only for the capabilities you need, on a metered-price basis. Once you’ve subscribed to an Email Add-on from the Mail Manager console, you can seamlessly incorporate it into your email workflows.
Email Add-ons extend Mail Manager’s core threat intelligence and security enforcement features on a per-workload basis, ensuring you have the right level of protection without over-provisioning resources. Within the Mail Manager console, you can explore detailed product descriptions, key benefits, and pricing information for each Add-on, empowering you to make informed decisions.
Key benefits of Add-ons:
Immediate use: no separate setup/integration work required.
Cost effective: pay for only what is needed and consumed, turn on and off as required
Granular deployment via individual traffic policy or rule action
Conclusion:
Amazon SES Mail Manager introduces advanced email routing and archiving features, providing significant benefits to customers. With customizable SMTP endpoints and recipient-oriented rule processing, customers gain precise control over email traffic, ensuring that rules are applied specifically to each recipient. The enhanced traffic policies improve email security and compliance, while the robust SMTP relay functionality seamlessly integrates with existing systems, ensuring efficient email routing and processing. Mail Manager’s archiving capabilities help meet regulatory requirements and simplify data management. Overall, Mail Manager streamlines email operations, optimizes infrastructure, and enhances reliability, security, and compliance, offering a powerful solution for managing complex email workflows.
About the Authors:
Jessica Fan is a Senior Product Manager at AWS, striving to improve the experience for Amazon SES customers. Outside of work, she enjoys long distance running, biking and bouldering.
Vinay Ujjini is an Amazon Pinpoint and Amazon Simple Email Service Worldwide Principal Specialist Solutions Architect at AWS. He has been solving customer’s omni-channel challenges for over 15 years. He is an avid sports enthusiast and in his spare time, enjoys playing tennis & cricket.
Version
3.20.0 of the Alpine Linux
distribution has been released with initial support for 64-bit
RISC-V. Other important changes include updates to GNOME 46, KDE Plasma 6, and replacing Redis with Valkey due to Redis’s adoption of a non-free
license model. See the release
notes for more on this release.
Looking up a virtual memory area (VMA) in a process’s address space, for
the handling of page faults or any of a number of other tasks, in
multi-threaded processes has long been bedeviled by lock contention in the
kernel. As a result, developer gatherings have been subjected to many
sessions on how to improve the situation. At the 2024 Linux Storage,
Filesystem, Memory-Management and BPF Summit, developers in the
memory-management track met, in a session led by Liam Howlett, to talk
about a situation that has improved considerably in recent times, but which
still offers opportunities for optimization.
Security updates have been issued by Debian (webkit2gtk), Fedora (kernel), Mageia (chromium-browser-stable, djvulibre, gdk-pixbuf2.0, nss & firefox, postgresql15 & postgresql13, python-pymongo, python-sqlparse, stb, thunderbird, and vim), Red Hat (go-toolset:rhel8, nodejs, and varnish:6), SUSE (gitui, glibc, and kernel), and Ubuntu (libspreadsheet-parseexcel-perl, linux-aws, linux-aws-5.15, linux-gke, linux-gcp, python-idna, and thunderbird).
We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce that the Spring 2024 System and Organization Controls (SOC) 1, 2, and 3 reports are now available. The reports cover the 12-month period from April 1, 2023 to March 31, 2024, so that customers have a full year of assurance from each report. These reports demonstrate our continuous commitment to adhere to the heightened expectations for cloud service providers.
The Spring 2024 SOC reports include an additional six services in scope, for a total of 177 services in scope. For up-to-date information, including when additional services are added, visit the AWS Services in Scope by Compliance Program webpage and choose SOC.
The six additional services in scope for the Spring 2024 SOC reports are:
AWS strives to continuously bring services into scope of its compliance programs to help you meet your architectural and regulatory needs. Please reach out to your AWS account team if you have questions or feedback about SOC compliance.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
If you have feedback about this post, submit comments in the Comments section below.
Vineeth Pillai gave a remote talk at the 2024 Linux Storage,
Filesystem, Memory Management, and BPF Summit explaining how BPF could be
used to improve the performance of virtual machines (VMs). Pillai has
a patch
set designed to let guest and host machines share scheduling information in
order to eliminate some of the overhead of running in a VM. The assembled
developers had several comments on the design, but seemed overall to approve of
the prospect.
When we launched Regional Services in June 2020, the concept of data locality and data sovereignty were very much rooted in European regulations. Fast-forward to today, and the pressure to localize data persists: Several countries have laws requiring data localization in some form, public-sector contracting requirements in many countries require their vendors to restrict the location of data processing, and some customers are reacting to geopolitical developments by seeking to exclude data processing from certain jurisdictions.
That’s why today we’re happy to announce expanded capabilities that will allow you to configure Regional Services for an increased set of defined regions to help you meet your specific requirements for being able to control where your traffic is handled. These new regions are available for early access starting in late May 2024, and we plan to have them generally available in June 2024.
It has always been our goal to provide you with the toolbox of solutions you need to not only address your security and performance concerns, but also to help you meet your legal obligations. And when it comes to data localization, we know that some of you need to have data stay in a particular jurisdiction, while others need data to avoid certain jurisdictions. In response to these needs, we’ve expanded our Regional Services toolbox of offerings to help you more precisely determine where traffic is inspected. Some of these new Regional Services offerings allow you to restrict inspection of data to only those data centers within jurisdictional boundaries, such as Brazil, Saudi Arabia, and Switzerland. Others will allow you to permit inspection of data everywhere except certain jurisdictions, such as our new Exclusive of Hong Kong and Macau offering and our Exclusive of Russia and Belarus offering. And we’ve also listened to customers who are eager to demonstrate their commitment to sustainability by offering our Cloudflare Green Energy region, which limits inspection of data to those data centers that are committed to powering their operations with renewable energy.
The new regions include some of our most requested areas and specifications:
Austria, Brazil, Cloudflare Green Energy, Exclusive of Hong Kong and Macau, Exclusive of Russia and Belarus, France, Hong Kong, Italy, NATO, the Netherlands, Russia, Saudi Arabia, South Africa, Spain, Switzerland, and Taiwan.
A full list of our Regional Services offerings can be found here.
A note on our framework for data localization going forward
Over the course of the next year, you are going to see new and exciting ways to use Cloudflare products to help keep your data local. But doesn’t this contradict the whole premise of Cloudflare? Aren’t we a global anycast network that believes in Region Earth?
We don’t believe these have to be an either/or conversation. While we continue to believe that data localization should not be a proxy for privacy and that restrictions on cross border data transfers are harmful to global commerce, we remain committed to supporting those of you who need data localization solutions to address your legal obligations and risk tolerance.
Unfortunately, many different cloud providers have decided that the best way to meet the compliance needs of their customers is to create fixed infrastructure deployments called sovereign clouds. The trouble with these infrastructure deployments is that you have to commit all of your traffic to be regionalized, regardless of whether all of that traffic actually needs to be confined to a specific data center in a specific region.
As we continue to ramp up development of our Data Localization Suite, I want to lay out the questions that are guiding our thought process:
What if there was a better way forward that lets you regionalize exactly what you need to, without having to localize everything, giving you the best of compliance and performance? What would customers build if they could localize the APIs that handled private customer information, while also serving their static assets globally? How could we increase the compliance and privacy of our customers’ Zero Trust deployments if we could let them choose where their security processing occurred? What if they could define custom regions, and apply those regions to specific hostnames and Cloudflare products while also being able to use BYOIP or Static IP?
We call this approach software defined regionalization (SDR) and we believe that it is the future of data localization. Using our global network as the foundation, SDR allows our customers to make exceptionally granular choices about what traffic to regionalize and where to regionalize it. This empowers you to build applications that are fast, reliable, and compliant without having to deploy new physical infrastructure or have multiple cloud deployments for the same application.
Taking it a step further, SDR allows you to shape Cloudflare to meet both current and future needs. It gives you the flexibility to quickly respond to new challenges in a rapidly changing world. By making localization choices in software, you are not bound by the physical constraints of your existing network geography or the locations of your cloud deployments.
We believe that software defined regionalization is the future of data localization, and we are excited to be on the forefront of its development.
How Regional Services ensures your data is processed in the correct region
Complying with data localization requirements isn’t possible without strong encryption; otherwise, anyone could snoop on your customers’ data, regardless of where it’s stored. Strong encryption is the foundation of Regional Services.
Data is often described as being “in transit” and “at rest”. It’s critically important that both are encrypted. Data “in transit” refers to just that – data while it’s moving about on the wire, whether a local network or the public Internet. “At rest” generally means stored on a disk somewhere, whether a spinning hard disk or a modern solid state disk.
In transit, Cloudflare can enforce that all traffic uses modern TLS and gets the highest level of encryption possible. We can also enforce that all traffic back to customers’ origin servers is always encrypted. Communication between all of our edge and core data centers is always encrypted.
Cloudflare encrypts all the data we handle at rest, with disk-level encryption. From cached files on our edge network, to configuration state in databases in our core data centers – every byte is encrypted at rest.
How then can we also regionalize the traffic if it’s encrypted? All of Cloudflare’s data centers advertise the same IP addresses through Border Gateway Protocol (BGP). Whichever data center is closest to an end user from a network point of view is the one that they will hit.
This is great for two reasons. The first is that the closer the data center is to an eyeball, the faster the reply. The second great benefit is that this comes in very handy when dealing with large DDoS attacks. Volumetric DDoS attacks throw a lot of bogus traffic at a particular application, which overwhelms network capacity. Cloudflare’s anycast network is great at taking on these attacks because they get distributed across the entire network, and mitigated close to where they originate.
Anycast doesn’t respect regional borders – it doesn’t even know about them. Which is why, out of the box, Cloudflare can’t guarantee that traffic from inside a country will also be serviced there. Typically, requests hit a data center inside the originating country, but it’s possible that the user’s Internet Service Provider will send traffic to a network that might route it to a different country.
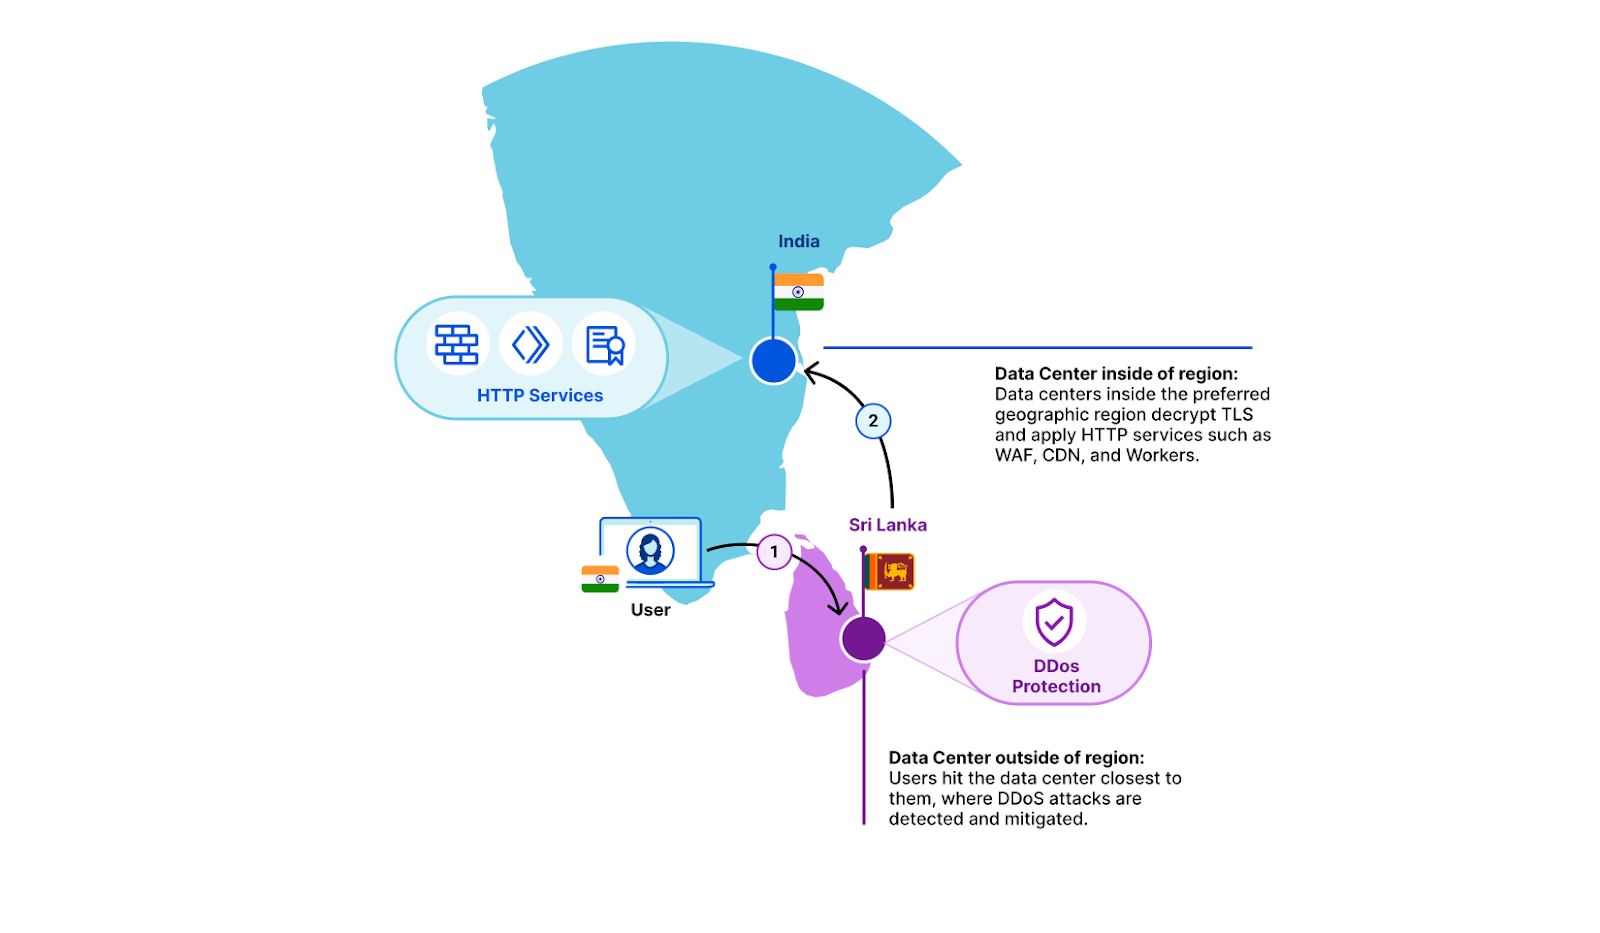
Regional Services solves that: when turned on, each data center becomes aware of which regional services-defined boundary it is operating in. If a customer’s end user hits a Cloudflare data center that doesn’t match the region that the customer has selected, we simply forward the raw TCP stream in encrypted form. Once it reaches a data center inside the right region, we decrypt and apply all of our Layer 7 products. This covers products such as CDN, WAF, Bot Management, and Workers.
Let’s take an example. A customer’s end user is in Kerala, India, and BGP has determined that the optimal data center for that end user’s request is in Colombo, Sri Lanka. In this example, a customer may have selected India as the sole region within which traffic should be serviced. The Colombo data center sees that this traffic is meant for the India region. It does not decrypt, but instead forwards it to a data center inside India. There, we decrypt and products such as WAF and Workers are applied as if the traffic had hit the data center directly. Responses from the in-region data center retrace the same path back to the client.
Our expanded Regional Services capabilities are available for early access in late May 2024, and we plan to have them generally available in June 2024. We are very excited about our ability to develop our Data Localization Suite to help you meet your data localization needs.
To get access to these expanded capabilities, or if you’re interested in using the Data Localization Suite, contact your account team.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


 Saurabh Bhutyani is a Principal Analytics Specialist Solutions Architect at AWS. He is passionate about new technologies. He joined AWS in 2019 and works with customers to provide architectural guidance for running generative AI use cases, scalable analytics solutions and data mesh architectures using AWS services like Amazon Bedrock, Amazon SageMaker, Amazon EMR, Amazon Athena, AWS Glue, AWS Lake Formation, and Amazon DataZone.
 Ankith Ede is a Data & Machine Learning Engineer at Amazon Web Services, based in New York City. He has years of experience building Machine Learning, Artificial Intelligence, and Analytics based solutions for large enterprise clients across various industries. He is passionate about helping customers build scalable and secure cloud based solutions at the cutting edge of technology innovation.
 Chandra Krishnan is a Solutions Engineer at Onehouse, based in New York City. He works on helping Onehouse customers build business value from their data lakehouse deployments and enjoys solving exciting challenges on behalf of his customers. Prior to Onehouse, Chandra worked at AWS as a Data and ML Engineer, helping large enterprise clients build cutting edge systems to drive innovation in their organizations.