Tag Archives: launch

Amazon DynamoDB now supports real-time vector search at any scale

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/amazon-dynamodb-now-supports-real-time-vector-search-at-any-scale/

Today, we’re announcing the general availability of vector search in Amazon DynamoDB. You can now store vector embeddings alongside your operational data in DynamoDB and run similarity searches directly against that data, without replicating it to a separate vector store.

DynamoDB supports native vector search with single-digit millisecond latency at 99%+ recall, and is designed for any scale, even trillions of vectors. There are no servers to provision, patch, or manage, and no software to install, maintain, or operate. The service has no versions, no maintenance windows, and zero downtime maintenance.

Vector indexes have no storage limits and scale horizontally as your data grows. You can now build applications that require semantic retrieval on agentic memory, retrieval augmented generation, recommendation engines, personalized experiences, anomaly detection, and more using DynamoDB and its native vector search.

If your application already uses DynamoDB, adding vector search previously required copying data into a dedicated vector database while maintaining a synchronization pipeline between the two services. This added operational overhead, data movement costs, licensing costs, and the challenge of maintaining predictable low latency at scale. With vector search built into DynamoDB, your vectors and operational data share the same serverless infrastructure and the same pay-per-request pricing model.

Vector search in DynamoDB introduces a new index type that you create on an attribute storing vector embeddings. You generate embeddings using a model of your choice, such as Amazon Bedrock Titan Text Embeddings, Cohere Embed, or OpenAI text embedding models, and store them as a list of floats in your table using a standard PutItem call. You then create a vector index on that attribute and specify the number of dimensions, the distance function, and any non-vector attributes you want to use as filters to narrow search results at query time. The SearchVectors API accepts a query vector, the number of results to return (up to 100), and optional filter conditions. It returns results ranked by similarity.

Use vector search in DynamoDB when your operational data already lives in DynamoDB and you want to add similarity search without provisioning a separate database or managing a synchronization pipeline. DynamoDB is fully serverless, so vector search scales automatically with no infrastructure to manage. It supports up to 4096 dimensions, Euclidean, Cosine, and Dot product distance functions, and inline filtering.

Getting started with vector search in DynamoDB
This walkthrough shows how to add vector search to an existing DynamoDB table using the DynamoDB console. The scenario contains an online sporting goods store with a product catalog table. Each item has standard operational attributes such as productId, category, description, marketplace, name, and price. The goal is to add semantic search so shoppers can find products using natural language queries rather than exact keyword matches.

1. Prepare DynamoDB table
To enable semantic search, I first generate vector embeddings for the product descriptions already in my table. Embeddings are numerical representations of text generated by a machine learning model that capture the meaning of the content. Two items with similar descriptions will have embeddings that are close to each other in vector space, which is what makes similarity search possible.
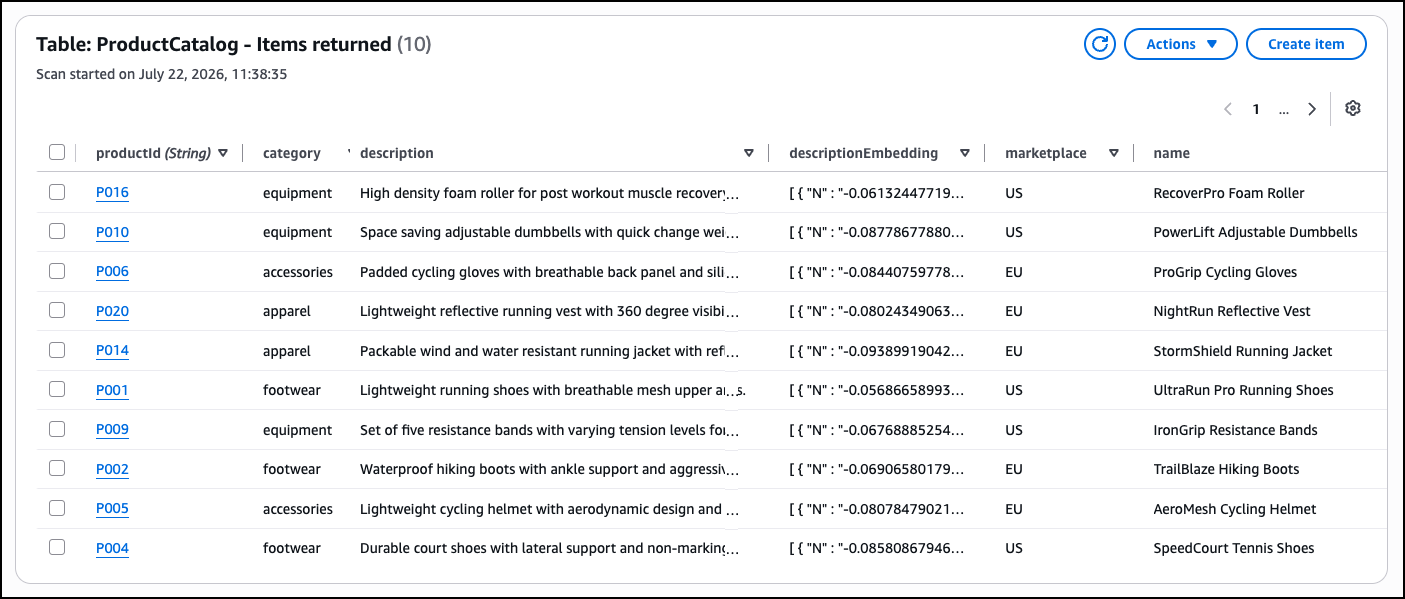
I can generate embeddings using Amazon Bedrock Titan Text Embeddings or another embedding model, then add them to my table using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDKs, AWS CloudFormation, or other infrastructure-as-code (IaC) tools.

For an existing table like ProductCatalog, I add the embeddings to each item as a new attribute named descriptionEmbedding using an UpdateItem call. DynamoDB stores vector embeddings using its existing List data type. Each element in the list is a Number that represents a single float value of the embedding vector. This means I do not need a new data type or schema change to start storing vectors alongside my existing operational attributes.

2. Create vector index
In the DynamoDB console, open the ProductCatalog table and choose the Indexes tab. I choose Create vector index. On the Create vector index page, I fill in the index details as follows. I enter ProductDescriptionIndex as the Index name and descriptionEmbedding as the Vector attribute.
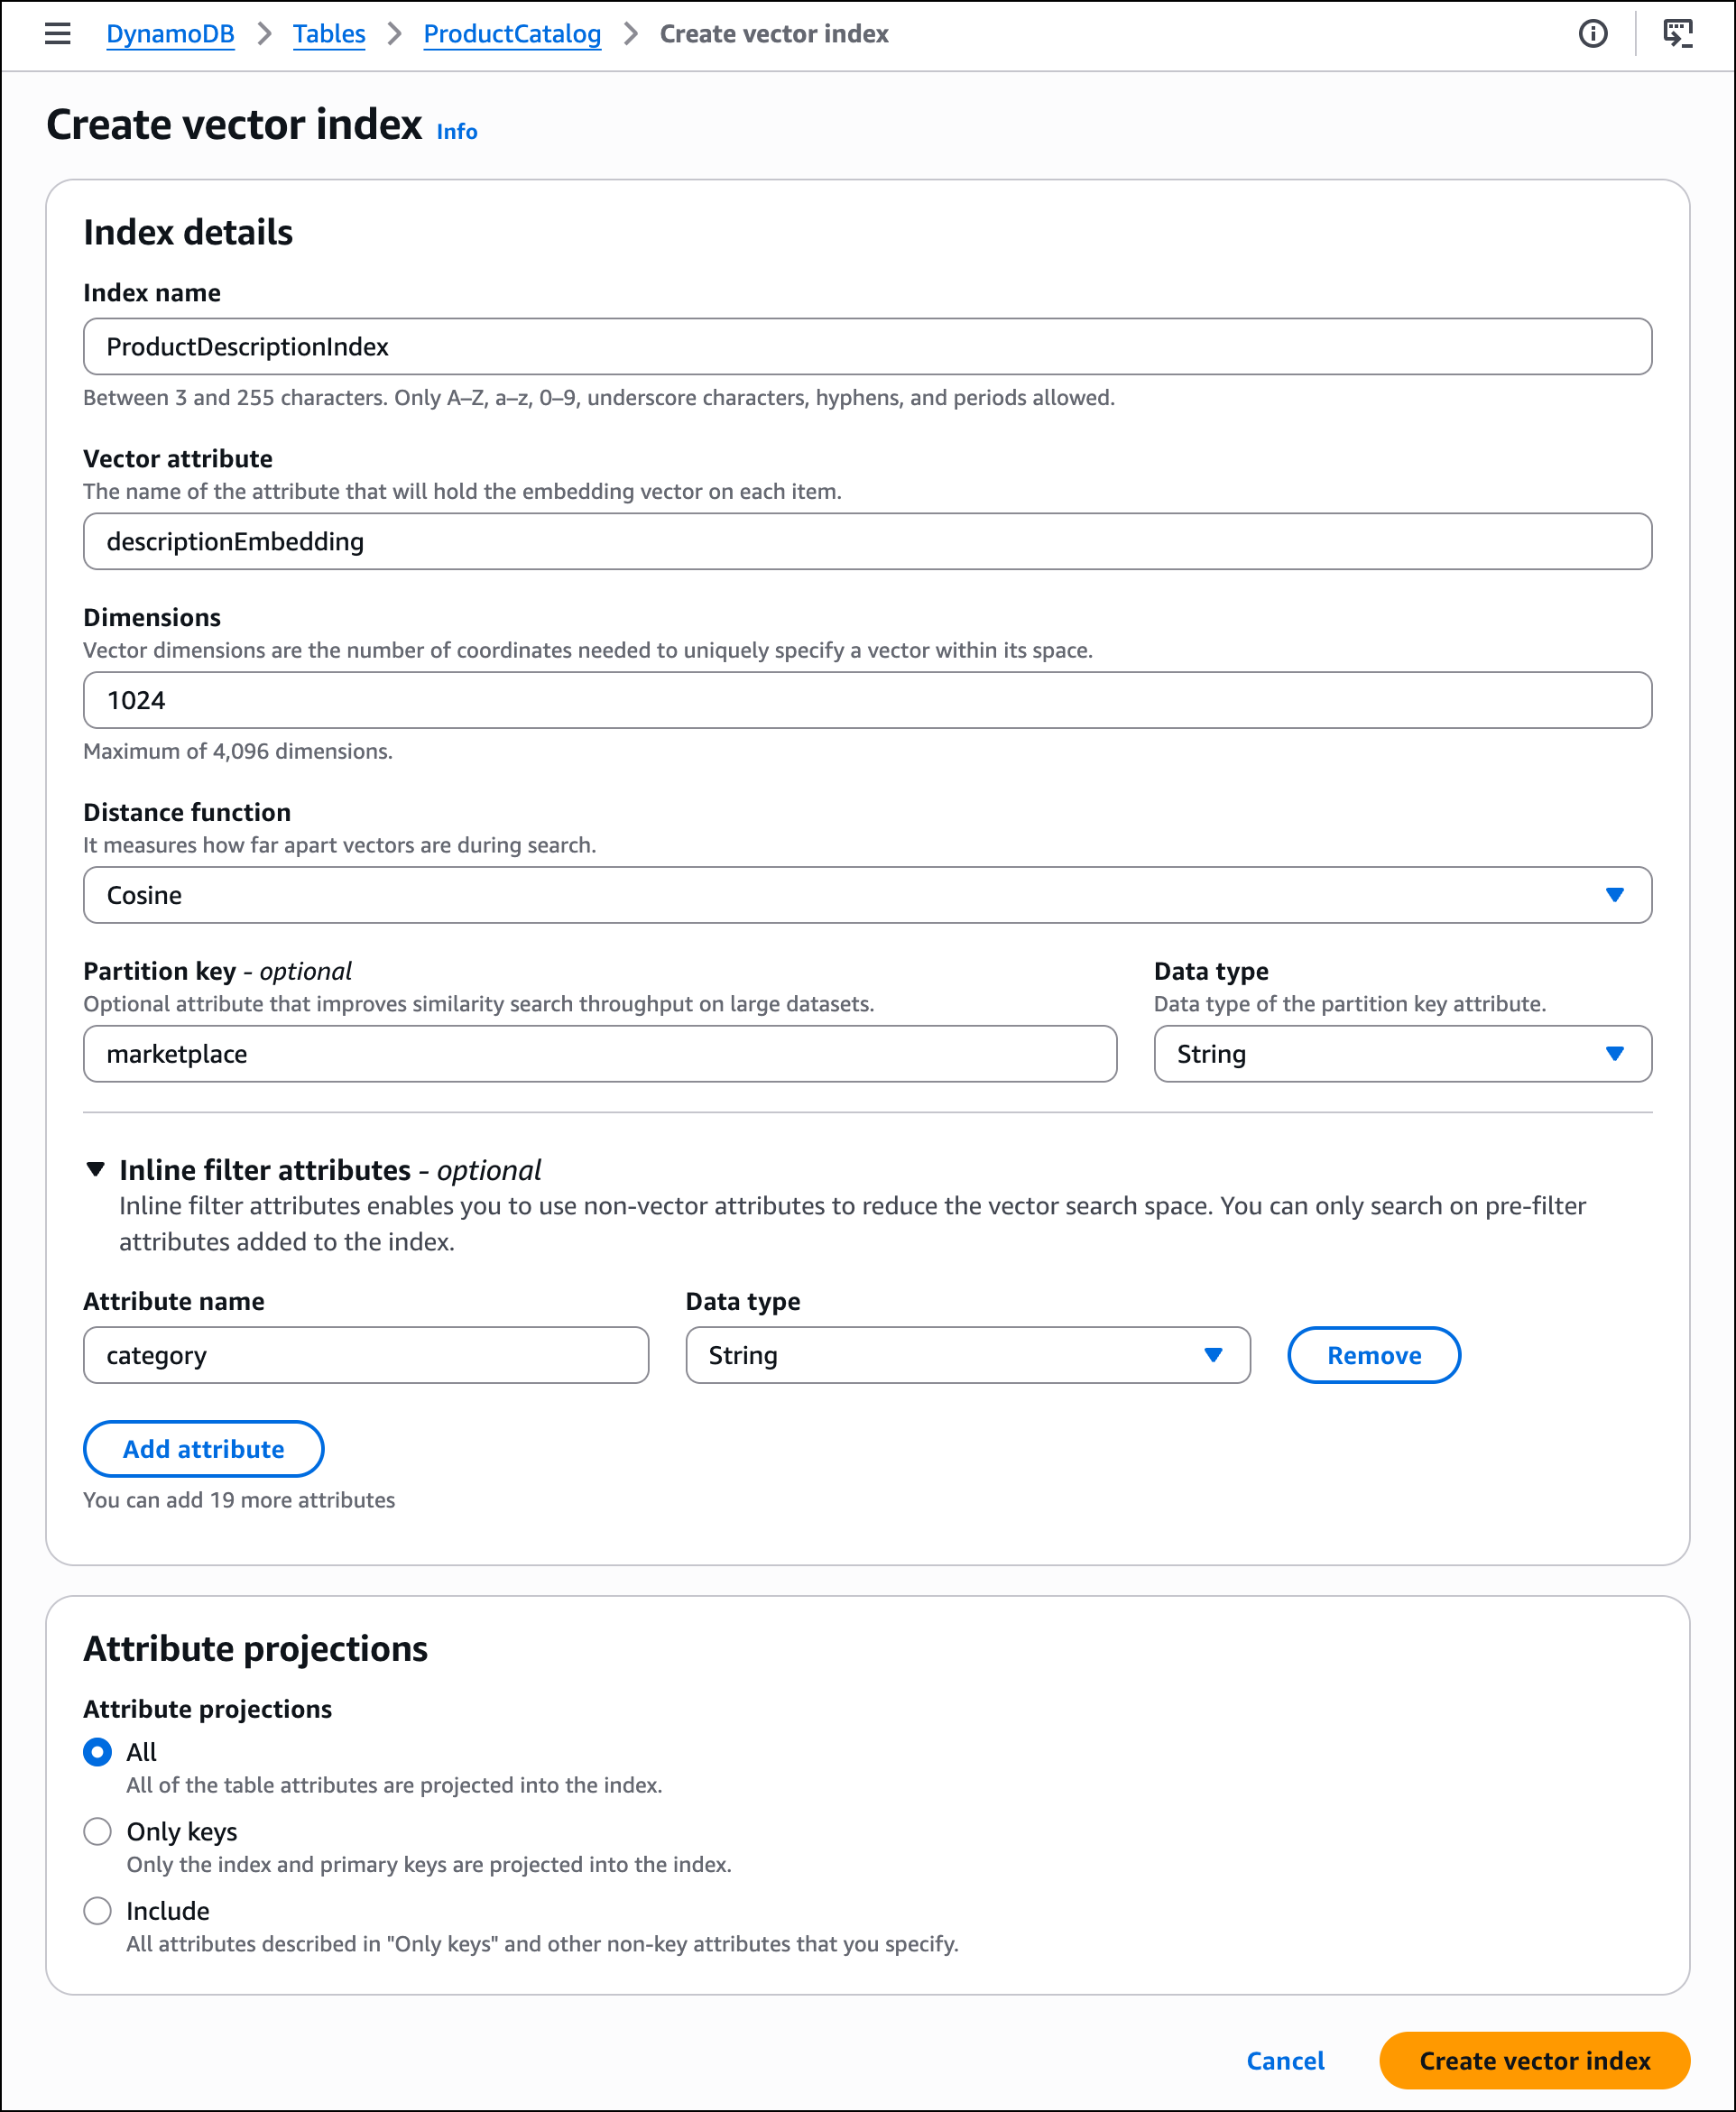
I enter the number of Dimensions that matches my embedding model’s output and select Cosine as the Distance function. Cosine measures the angle between vectors rather than their magnitude, which makes it effective for comparing semantic similarity of text embeddings. Vector search in DynamoDB also supports Euclidean and Dot product distance functions.

  • Euclidean: Use when the magnitude of the vectors is meaningful, such as clustering items by a numeric value like purchase count.
  • Dot product: Use when both direction and magnitude matter, such as in recommendation systems that weight interest alignment and frequency together. As a general rule, match the distance function to the one used to train your embedding model for the best accuracy.

I enter marketplace as the Partition key. The vector index partition key controls how DynamoDB distributes vectors across partitions, allowing the index to scale out while maintaining predictable latencies. Each search is scoped to a single partition key value, so a product catalog serving multiple marketplaces can search within one marketplace’s inventory without scanning the entire index. The partition key is optional, but recommended for large datasets with high query throughput.

I expand Inline filter attributes and add category as a filter attribute. This helps me narrow search results to a specific product category at query time. Filter conditions support exact-match values only; range conditions such as BETWEEN or BEGINS_WITH are not supported. I leave Attribute projections set to All so that all table attributes are returned with my search results. Choose Create vector index and wait for the index status to change to Active.

3. Run vector search
I generate a query vector from a natural language search term such as “lightweight running shoes for summer” using the same embedding model I used for the product descriptions. In the DynamoDB console, I choose Explore items in the left navigation pane and select the ProductCatalog table.

Choose Search to switch to vector search mode. I select ProductDescriptionIndex from the Select a vector index dropdown, paste the query vector into the Search vector field, and set Number of results (Top K) to 5. I enter US as the Partition key value to scope the search to the US marketplace. I expand Inline filter attributes and set category equal to footwear to narrow the search to footwear products only. Now, choose Run.
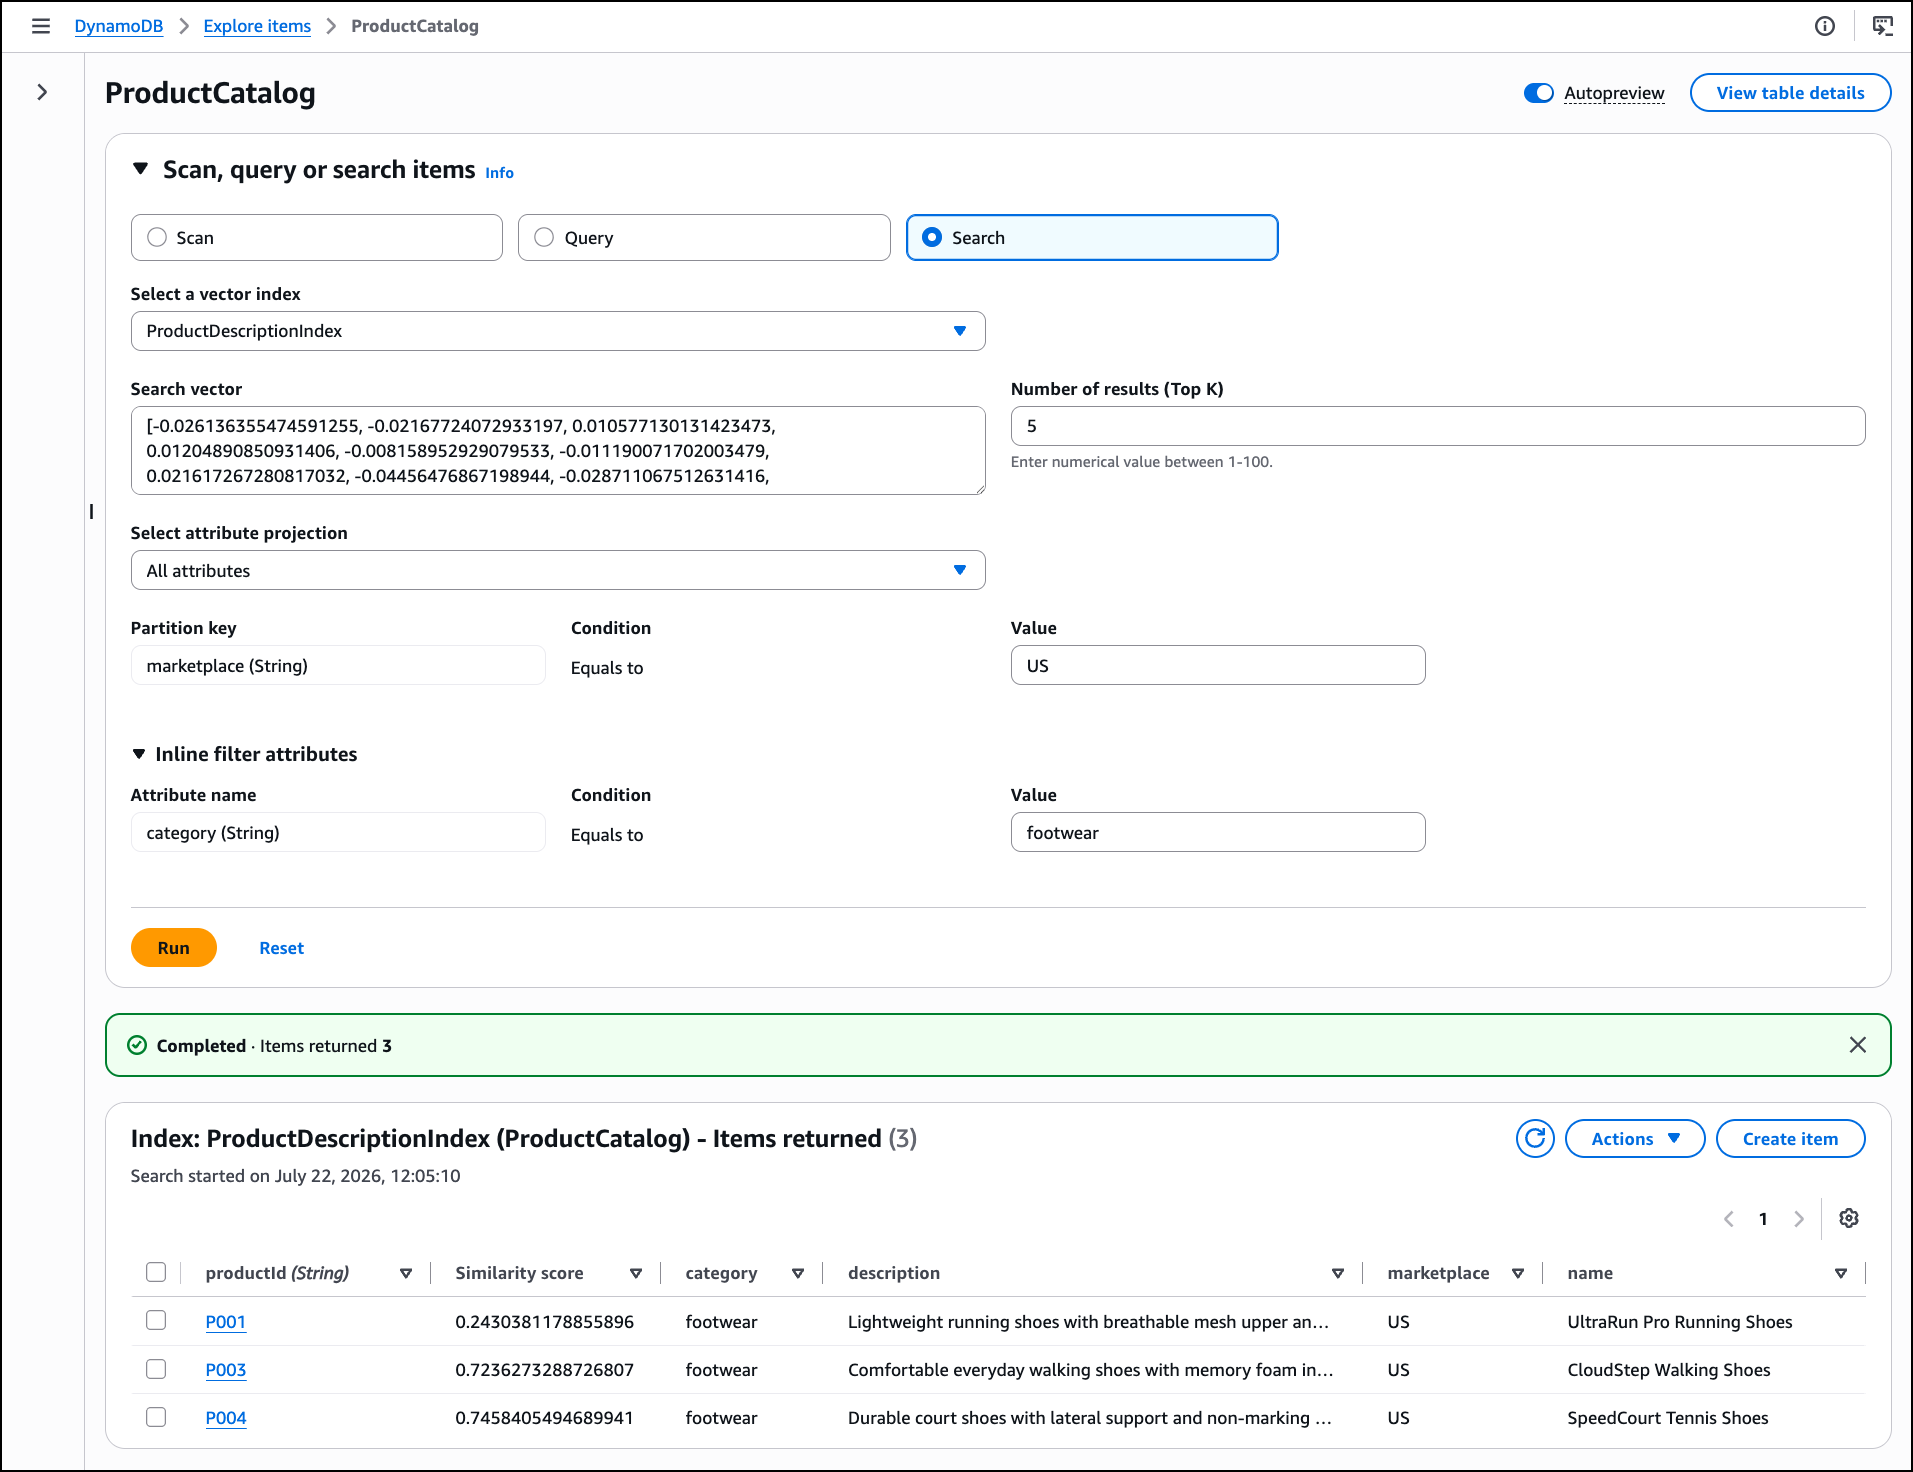
DynamoDB returns the five most semantically similar products in the footwear category, ranked by similarity score, alongside the standard operational attributes such as name and price in the same response. The similarity score’s meaning depends on the distance function selected for the index. For Cosine and Euclidean distance functions, lower similarity score values indicate higher similarity, with a score of 0 indicating identical vectors. For the dot product distance function, higher similarity score values indicate higher similarity.

To interact with vector search programmatically, including calling APIs and searching documentation, try the AWS MCP Server and plugins with your preferred AI coding tool. To learn more, visit the Amazon DynamoDB Developer Guide.

Get started today
Vector search in Amazon DynamoDB is generally available in all commercial AWS Regions, including the AWS GovCloud (US) Regions. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. For pricing details, visit the Amazon DynamoDB pricing page.

Start exploring vector search in DynamoDB today and send feedback to AWS re:Post for Amazon DynamoDB or through your usual AWS Support contacts.
— Esra

Analyze and remediate technical debt autonomously with AWS Transform – continuous modernization

Post Syndicated from Ritik Khatwani original https://aws.amazon.com/blogs/devops/analyze-and-remediate-technical-debt-autonomously-with-aws-transform-continuous-modernization/

Introduction

In a recent post, my colleague Micah Walter introduced AWS Transform – continuous modernization in public preview. Today, this capability is generally available in regions supported for AWS Transform .

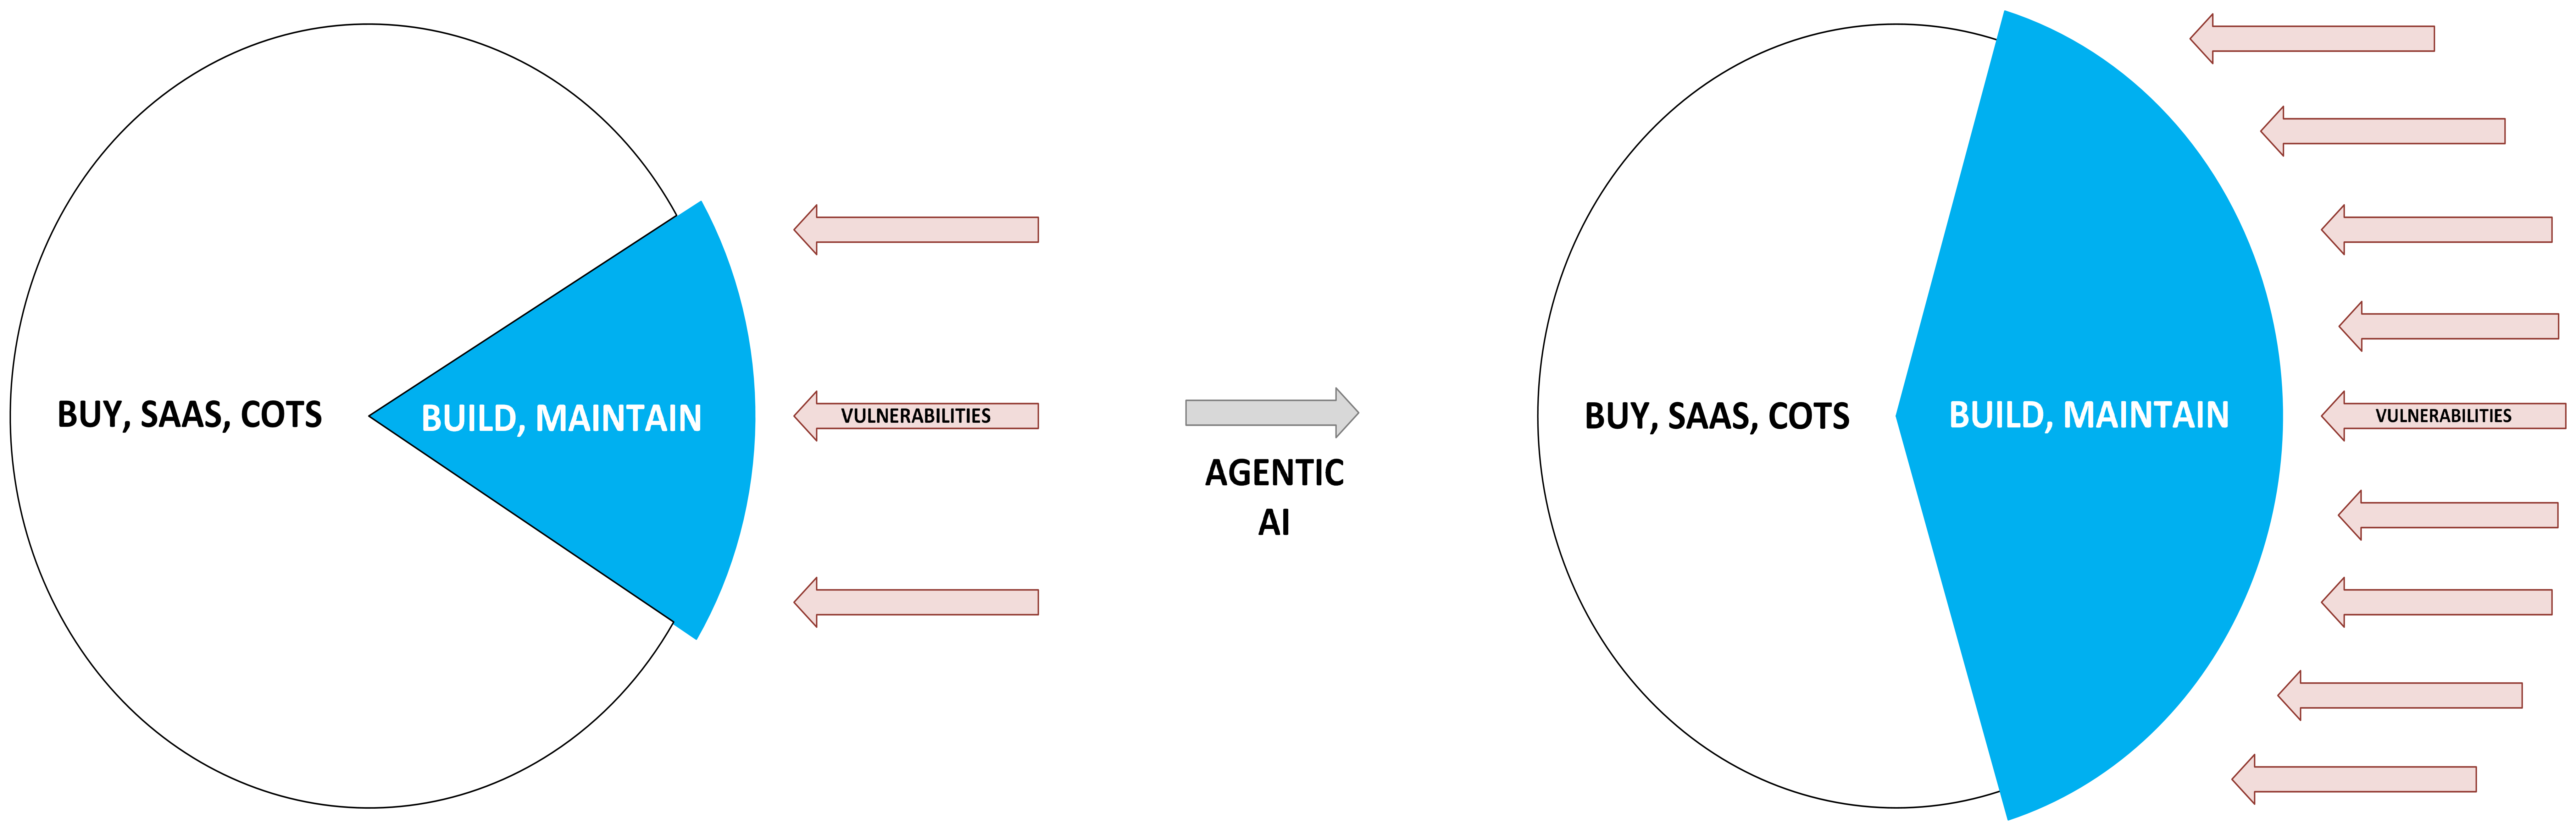
Development velocity continues to increase. But velocity without maintenance accumulates technical debt at speed. The faster software scales, the faster technical debt compounds. At the same time, more sophisticated exploits and attack vectors are emerging – and the risk is increasing (Figure 1). For organizations, this makes staying on top of tech debt and maintaining a strong security posture across an increasing sphere of responsibility not only important, but business-critical.

Two pie-circle diagrams connected by an arrow labeled "AGENTIC AI." In the left circle, most of the area is labeled "BUY, SAAS, COTS" while a small blue wedge labeled "BUILD, MAINTAIN" faces three arrows labeled "VULNERABILITIES." In the right circle, the blue "BUILD, MAINTAIN" section has grown to roughly half the circle and faces many more vulnerability arrows, illustrating how agentic AI expands the amount of code organizations build and maintain — and the corresponding vulnerability surface.

Figure 1: Changing landscape of software maintenance

To contend with compounding technical debt, engineering organizations have typically stitched together point tools, spent app-by-app cycles wasting engineering capacity, and relied on self-reports for status that lags reality and hides regressions.

This is the problem continuous modernization capability was built to solve: shift code transformation from a periodic project into an automated, always-on practice. Rather than scheduling modernization sprints or relying on manual audits, your repositories are analyzed on demand or on a recurring schedule, with findings prioritized by severity and impact, and validated pull requests are generated autonomously to resolve them.

In this post, I’ll recap the preview launch and then I’ll walk you through additional capabilities we’ve added since. I’ll also show how you can use it today to get started.

What continuous modernization provides

AWS Transform – continuous modernization connects to your source control systems (GitHub, GitLab, Bitbucket, or local repositories), scans repositories, and generates prioritized findings. At your direction, it autonomously creates pull requests with validated code changes.

The capability supports several analysis types:

  • Rapid tech debt analysis: fast metadata-only scans of package manifests (pom.xml, package.json, requirements.txt) to identify stale versions and outdated dependencies
  • Comprehensive tech debt analysis: deep code-level analysis examining source code for debt patterns, code quality issues, architecture concerns, and improvement opportunities
  • Security analysis: Common vulnerability detection within the source code and dependencies via AWS Security Agent (now part of AWS Continuum)
  • Agentic readiness: assesses your code base readiness for agent integration
  • Modernization readiness: evaluates candidates for containerization, serverless migration, and platform upgrades
  • Custom analysis: run your own transformation definition as an analysis, including organization-specific policies your platform team already enforces

You can run these analyses on demand or schedule them on a recurring cadence. The system accumulates findings over time, giving you trend data and portfolio-wide visibility that periodic manual audits can’t match.

Initiate and schedule recurring analysis from the AWS Transform web app

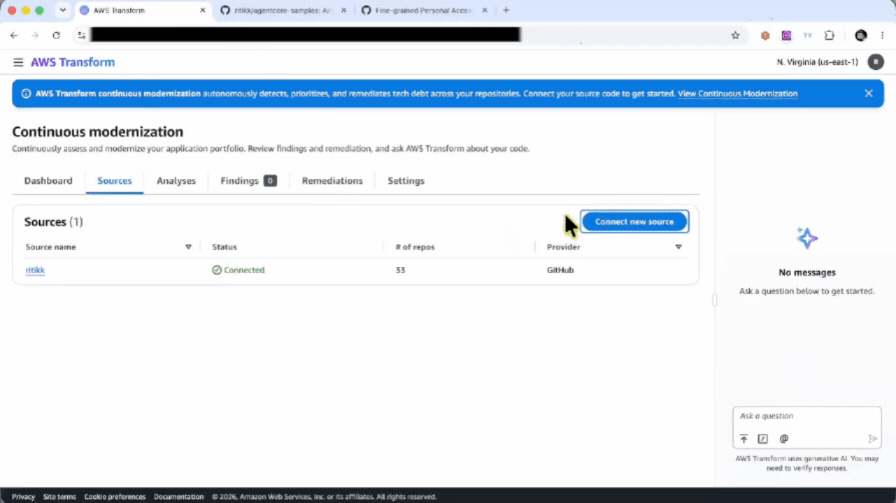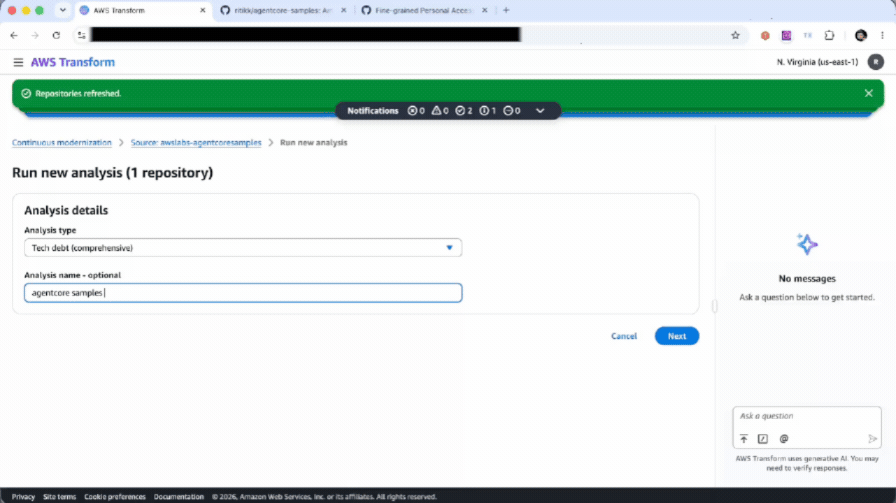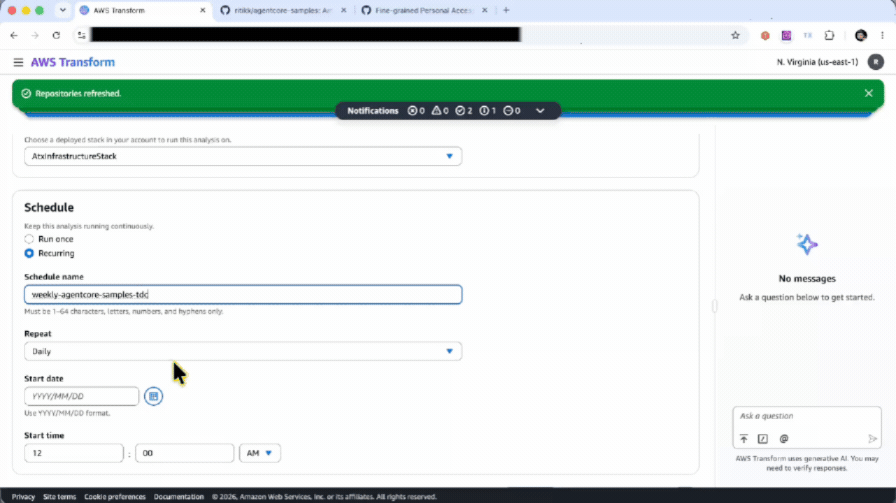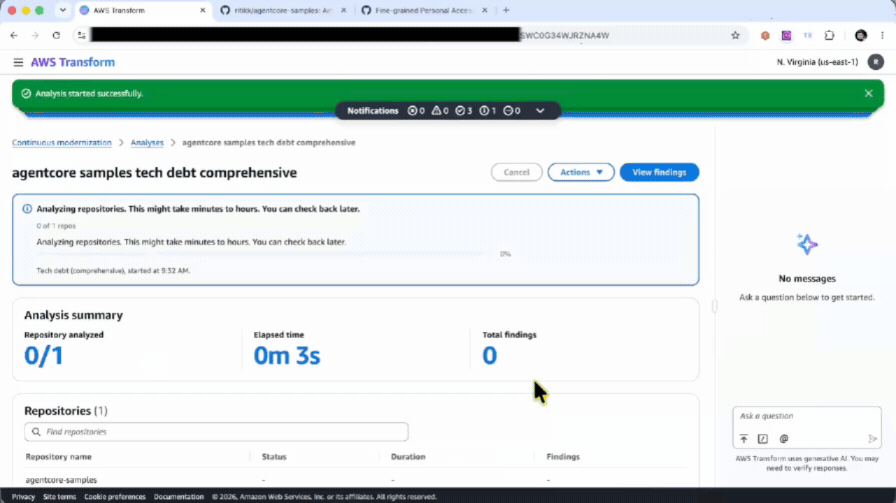
We’re excited to add the ability to connect your source code management (SCM) provider and initiate an analysis directly from the AWS Transform web application so you can get value from real insights faster than before (Figure 2). You can also schedule recurring analysis, review findings, and create remediations from within the web app. To learn more about the web app and how to set it up, see AWS Transform web application.

Screen recording of the AWS Transform Continuous Modernization console (N. Virginia region). A "Connect new source" dialog is filled in with GitHub as the provider, then repositories refresh and "agentcore-samples" is selected from the awslabs-agentcoresamples source. A new analysis is configured with type "Tech debt (comprehensive)" and named "agentcore samples tech debt comprehensive." In the Schedule step, "Recurring" is chosen with a weekly cadence on Mondays, a start date of 2026/07/28, and a start time, ending with the "Run now and schedule" button.

Figure 2: Set up continuous modernization in the AWS Transform web application

Interact via your IDE or terminal with the new CLI and developer tools

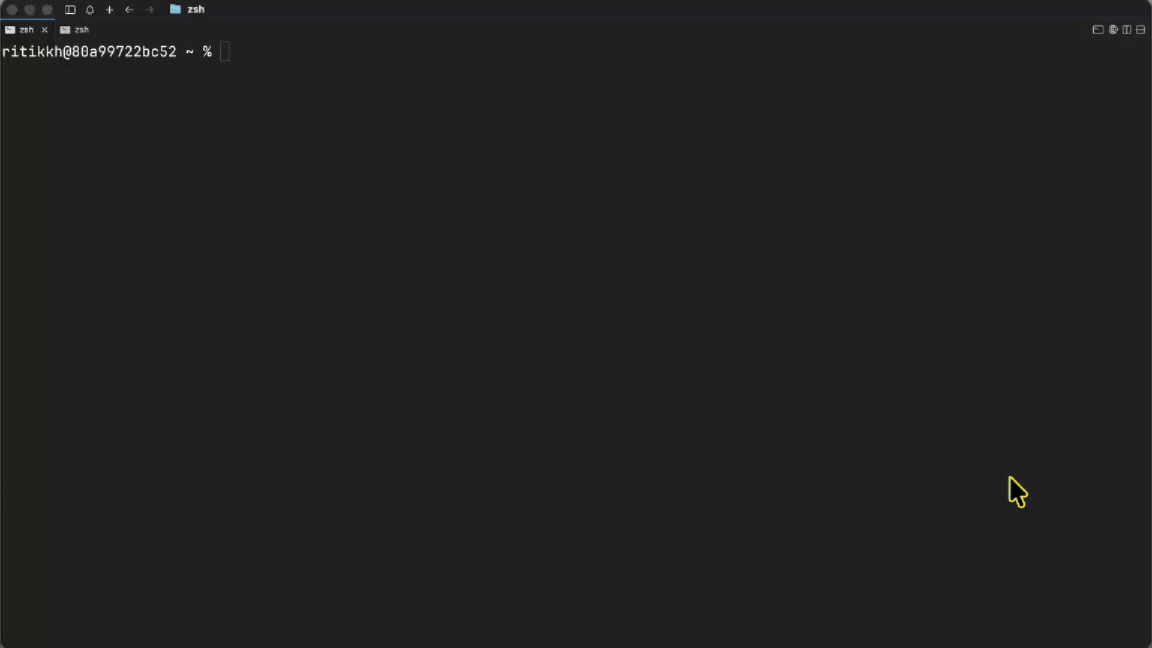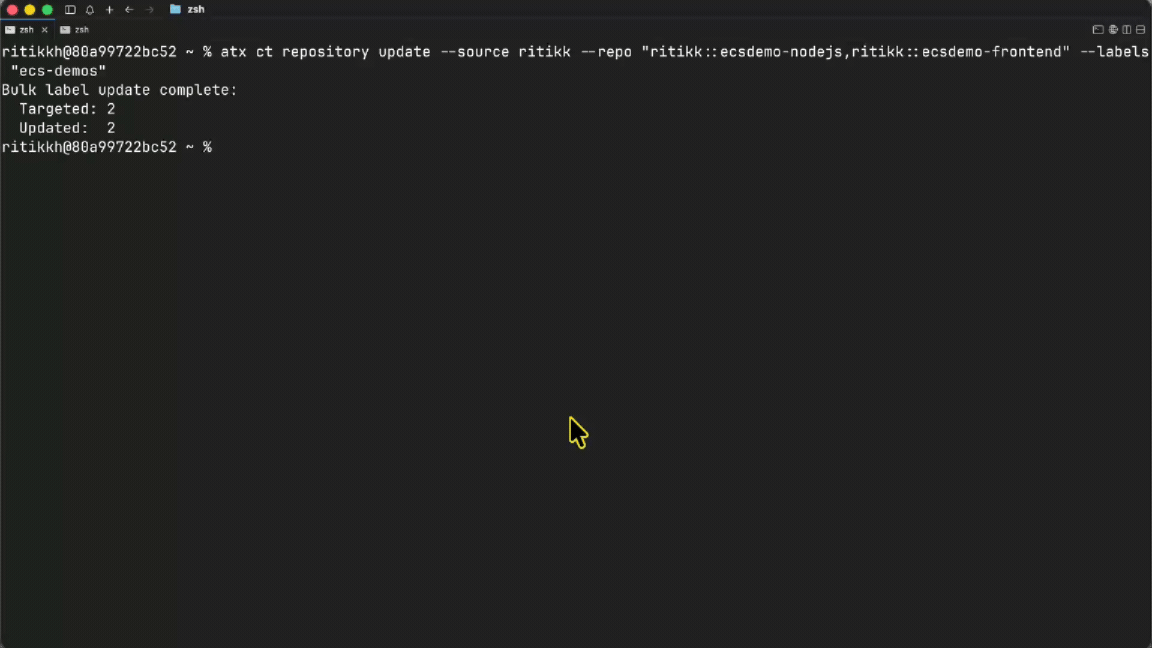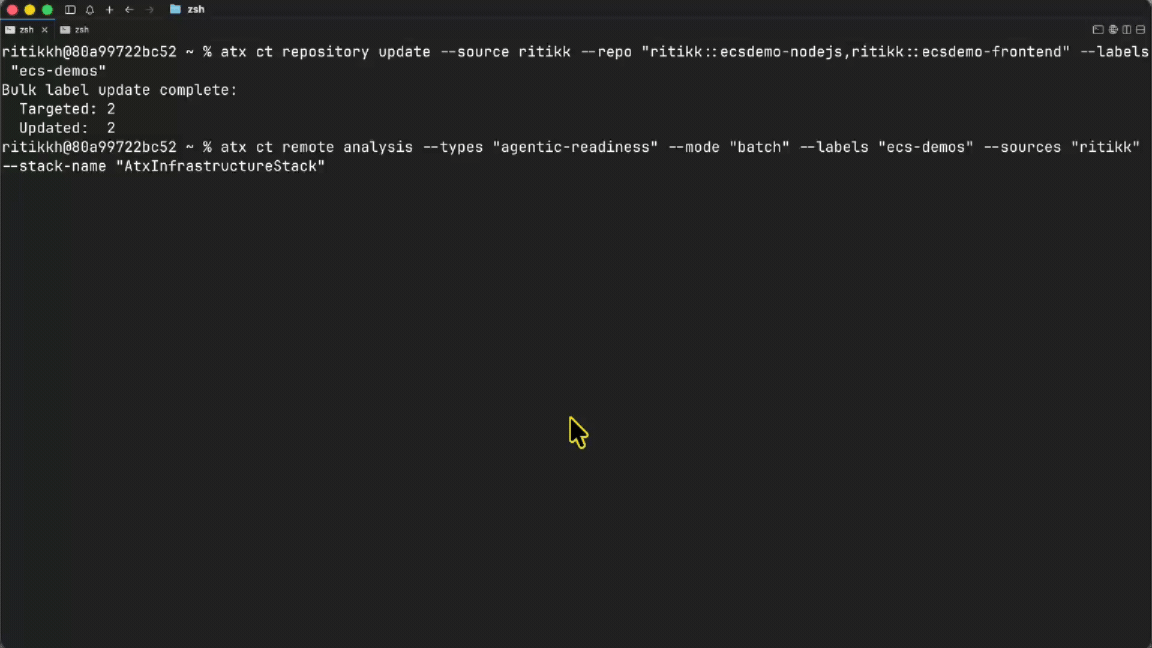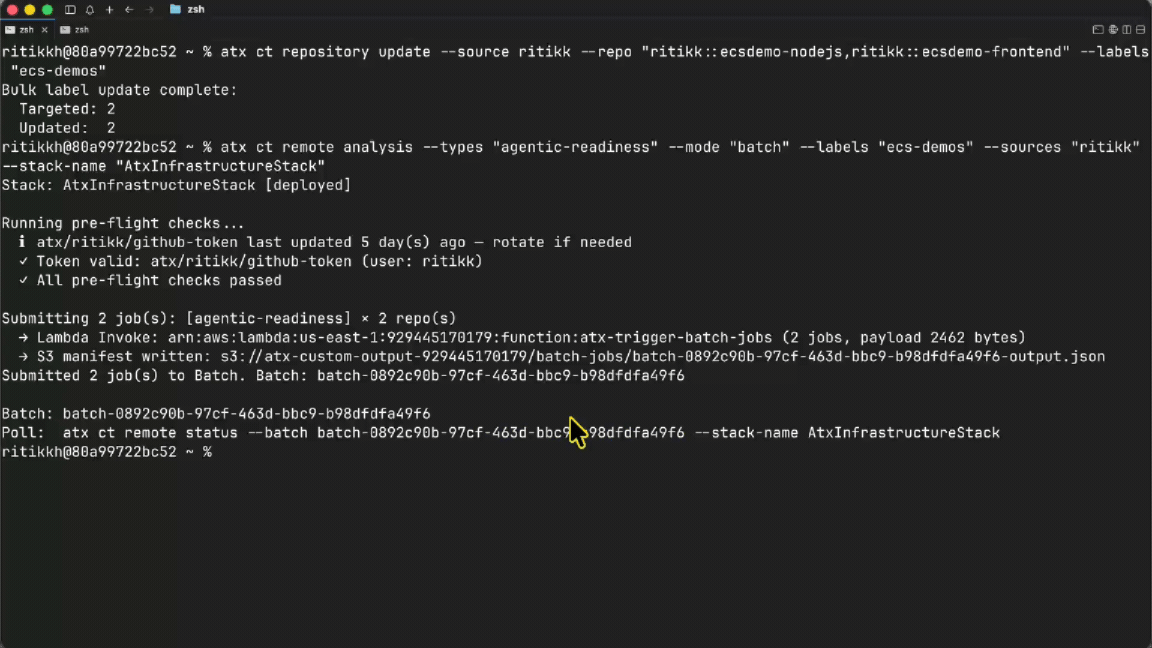
The new version of the AWS Transform CLI and it’s atx ct(v3.8.0) introduce additional capabilities that simplify how you setup and work with continuous modernization. The new atx ct remote sub-commands allow you to provision infrastructure and run scheduled analyses and remediations with Amazon Elastic Compute Cloud (Amazon EC2) and AWS Batch (Figure 3). To learn more about the CLI commands, refer to working with continuous modernization. The updated AWS Transform Kiro power and plugin make it even easier to configure your source repositories and run analyses directly from your IDE or terminal. To learn more, see developer tools.

You can also leverage labels with your repositories to group them and organize operations in batches. In the example below, I create a subset of repositories from my GitHub organization that I want to run agentic readiness analysis on and trigger a one-time analysis.

Screen recording of a macOS zsh terminal running AWS Transform CLI commands. First, atx ct repository update tags two repositories (ritikk::ecsdemo-nodejs and ritikk::ecsdemo-frontend) with the label "ecs-demos"; the output confirms "Bulk label update complete: Targeted 2, Updated 2." Then atx ct remote analysis --types "agentic-readiness" --mode "batch" --labels "ecs-demos" --sources "ritikk" --stack-name "AtxInfrastructureStack" kicks off a batch analysis. Pre-flight checks pass, a Lambda function is invoked, an S3 manifest is written, and two jobs are submitted to Batch with a batch ID and a poll command shown to check status.

Figure 3: Use the AWS Transform cli to analyze your repositories

Real-world results

Across industries, partners and enterprises are already seeing the impact of continuous modernization. The results speak to a consistent theme: what used to take months of manual effort now happens in minutes, at a scale that was previously impractical with manual review.

From weeks of manual assessment to insights in days

Quantiphi ran continuous modernization across a large portfolio and compressed a multi-week assessment into a matter of days:

“At Quantiphi, we’re helping enterprises accelerate application modernization through AI-powered engineering. Using AWS Transform continuous modernization, we analyzed more than 500 repositories and uncovered over 3,000 technical debt findings in less than a week, a time frame that traditionally required nearly three weeks of manual assessment. By automating technical debt discovery and providing actionable remediation insights, we reduced assessment effort by more than 60%, accelerated modernization planning, and enabled our customers to focus engineering investments on innovation instead of analysis. We believe AWS Transform continuous modernization is a foundational capability for delivering continuous, AI-driven enterprise modernization at scale.”

Sanchit Jain, Migration and Modernization Practice Leader, Quantiphi AWS Practice

Shifting from reactive maintenance to proactive modernization

For Hexaware, the value is in continuously surfacing what needs attention across large portfolios, so teams can get ahead of debt rather than react to it:

“At Hexaware, we’re constantly looking for ways to help clients modernize faster while controlling cost and complexity. AWS Transform continuous modernization provides a scalable approach to identifying technical debt, modernization opportunities, and AI-readiness gaps across large application portfolios. By automating analysis and continuously surfacing remediation recommendations, organizations can shift from reactive maintenance to proactive modernization. This capability has the potential to significantly accelerate transformation roadmaps and help enterprises build more resilient, future-ready applications, very quickly.”

Inderjeet Gurtatta, Vice President, Hexaware Technologies

An 80 percent reduction in assessment time

Tech Mahindra measured the impact directly, cutting assessment time from 40 hours to 8 across 25 repositories:

“Achieving an 80 percent reduction in assessment time, from 40 hours down to 8, across 25 enterprise repositories is just the beginning of what we see as a transformative shift in how organizations approach continuous modernization. AWS Transform’s scanning and analysis engine is solid, and the structured output allows our teams to validate findings quickly and build prioritized remediation plans with confidence. As the platform matures with features like scan resume capabilities and broader platform support, we expect to embed AWS Transform continuous modernization into our standard delivery methodology while maintaining the depth and accuracy our enterprise clients demand.”

Sanjeev Agarwal, Global Head of AWS Business, Tech Mahindra

Uncovering risks that traditional scanners miss

Cybage found that the continuous modernization capability surfaced hidden security risks that conventional scans overlooked, then fed those findings into their own delivery framework:

“AWS Transform continuous modernization completes codebase analysis in under an hour, work which normally takes weeks, while uncovering risks that traditional scanners miss like disabled security warnings, vulnerable code copied into applications, and security controls intentionally switched off. Cybage’s CLEAR Framework builds on these findings by converting them into a prioritized, customer-specific modernization plan with confidence scoring, technical-debt measurement, and integration with tools like GitHub, Jira, and SonarQube. Together, AWS Transform discovers hidden risks at speed, and CLEAR determines what matters most and how teams move from analysis to execution.”

Mohammad Mahdee-uz Zaman, Vice President, AWS Strategic Alliances, Cybage Software Inc.

Straight from discovery to a concrete migration plan

3Pillar moved directly from discovery to an actionable migration plan:

“For most IT leaders, application modernization is the bane of their existence. We put AWS Transform continuous modernization to the test across more than 25 repos, and came away very impressed. Analysis that would have taken our engineers an estimated 3-4 weeks of manual code reviews surfaced in an hour, uncovering over 190 tech debt findings, including outdated dependencies, dead code, and migration risks. The service’s ability to build migration rules purpose-built for each repo let us move straight from discovery to a concrete migration plan, without weeks of manual mapping. Based on our testing, we estimate AWS Transform continuous modernization can cut 40-50% off the overall modernization lifecycle. This speed means tech leaders can embark on modernization initiatives with confidence that it won’t drag on for many years.”

Pankaj Chawla, CTO, 3Pillar

Conclusion

AWS Transform – continuous modernization helps you go from one-off projects and campaigns to a fully operational tech debt management program: connecting sources, running analyses, triaging findings, launching remediation campaigns, and scheduling recurring scans. The web app dashboard and reports provide prioritization signals directly from your code. When a repository diverges from your baseline, the next analysis can surface the change and help teams understand its severity and breadth. This reduces reliance on manual status collection and periodic code-health audits.

To get started, you can access the capability through the AWS Transform Kiro power, the AWS Transform web application, or directly via the atx ct CLI. To learn more, visit the AWS Transform documentation.

Ritik Khatwani

Ritik Khatwani

Ritik is a Sr Worldwide Specialist Solutions Architect at AWS based in New York City. He has deep expertise in software engineering and currently works with customers to modernize their development workflows using generative AI.

Introducing Amazon Simple Email Service (SES) pricing plans

Post Syndicated from Advait Gomkale original https://aws.amazon.com/blogs/messaging-and-targeting/introducing-amazon-simple-email-service-ses-pricing-plans/

Businesses rely on email to deliver critical notifications, nurture customer relationships, and grow revenue. But their success depends on more than just sending the right message. It depends on emails getting delivered to the inbox and ultimately getting read. When emails land in spam or go unread, the business impact is real and measurable: missed engagement, eroded customer trust, and lost revenue.

Most email providers offer capabilities to help improve deliverability, including dedicated sending infrastructure, reputation monitoring, address validation, and inbox placement testing. But these capabilities are typically sold as individual add-ons, each priced separately. Reaching the inbox consistently shouldn’t require evaluating dozens of options independently.

That changes today with Amazon SES pricing plans. Pick a plan, and the right capabilities are already included at up to 22% less than purchasing them individually.

Amazon SES pricing plans

Amazon SES offers three plans: Essentials, Pro, and Enterprise. Each builds on the one before it, offering more capability, so you choose the one that fits your email needs.

Essentials

Get started with Amazon SES. Monitor how emails perform and get insights to help improve deliverability over time.

Send email reliably at scale and see what’s happening: which emails are landing, which are bouncing, and what needs attention. Essentials gives you the data and recommendations to guide your improvements, with the flexibility to upgrade to Pro as your deliverability needs grow.

Pro

Get higher deliverability with dedicated infrastructure and proactive reputation protection. Reach the inbox consistently as sending scales.

Pro shifts deliverability from reactive to proactive. With Pro, your sending runs on dedicated IPs, keeping your reputation isolated from other senders. Invalid addresses are caught before they bounce, and you see inbox placement across providers your domains send through, not just within SES. Pro helps you prevent problems, not just discover them after the fact.

Enterprise

Get the most out of Amazon SES. Reach the inbox reliably, stay resilient globally, and isolate sending reputation across workloads.

Everything in Pro, plus resilience that keeps email flowing if a region goes down, reputation isolation across separate workloads, and an annual deliverability assessment. This is the most comprehensive SES experience available.

For full pricing details and a complete feature comparison across all three plans, visit the Amazon SES Pricing page.

Getting started

Starting July 21, 2026, all new SES accounts begin on the Essentials plan. Returning customers who have not sent or processed email through SES since June 1, 2025 also begin on the Essentials plan. From there, you can upgrade to Pro or Enterprise, or switch to à-la-carte pricing at any time. Customers who have sent or processed email through SES on or after June 1, 2025 remain on à-la-carte pricing and can switch to a plan anytime.

If you are new to AWS, the AWS Free Tier provides up to $200 in credits during your first six months that you can apply toward Amazon SES pricing plans. As of July 21, 2026, the SES-specific free tier (3,000 email message charges per month for your first 12 months after first SES use) is no longer available for new customers. If you are currently on the SES-specific free tier, your benefits continue for the remainder of your 12-month period.

To get started, sign in to the Amazon SES console and navigate to the Pricing plan section. To learn more, visit the Amazon SES Pricing page or explore the Amazon SES documentation.


About the Authors

Amazon SQS turns 20: Two decades of reliable messaging at scale

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/amazon-sqs-turns-20-two-decades-of-reliable-messaging-at-scale/

On July 13, 2006, we launched Amazon Simple Queue Service (Amazon SQS) as one of the first three services available to customers, alongside Amazon EC2 and Amazon S3. We had learned firsthand that distributed systems need a reliable way to pass messages between components without creating tight dependencies. If one service called another directly and that service was slow or unavailable, failures cascaded through the entire system. Message queuing solved this by letting services communicate asynchronously: a producer could drop a message into a queue and move on, while a consumer picked it up when ready. This approach kept individual service failures from affecting the rest of the system.

When Amazon SQS launched publicly in July 2006, it made this pattern available to every AWS customer. Twenty years later, that core function, decoupling producers from consumers, remains the reason customers use SQS. The scale, performance, and operational controls around it look very different now though.

Jeff Barr covered the first 15 years of SQS milestones in his 15th anniversary post, from the original 8 KB message limit in 2006 through FIFO queues, server-side encryption, and Lambda integration. Over the last five years, we have continued to scale SQS, added stronger security defaults, and introduced new capabilities that address increasingly complex workload patterns.

Key milestones between 2021 and 2026
High throughput mode for FIFO queues (2021): In May 2021, we launched general availability of high throughput mode for FIFO queues, supporting up to 3,000 transactions per second (TPS) per API action, a tenfold increase over the previous limit. We continued raising this ceiling over the following two years: to 6,000 TPS in October 2022, to 9,000 TPS in August 2023, and to 18,000 TPS in October 2023, before reaching 70,000 TPS per API action in select Regions by November 2023.

Server-side encryption with SSE-SQS (2021): In November 2021, we introduced server-side encryption with Amazon SQS-managed encryption keys (SSE-SQS), giving customers an encryption option that required no key management. In October 2022, we made SSE-SQS the default for all newly created queues, so customers no longer needed to explicitly enable it.

Dead-letter queue redrive enhancements (2021): We progressively expanded how customers recover unconsumed messages from dead-letter queues. In December 2021, we added DLQ redrive to source queue directly in the SQS console. In June 2023, we extended this capability to the AWS SDK and CLI through new APIs, including StartMessageMoveTask, CancelMessageMoveTask, and ListMessageMoveTasks. In November 2023, we added redrive support for FIFO queues.

Attribute-based access control, ABAC (2022): In November 2022, we introduced ABAC, giving customers the ability to configure access permissions based on queue tags rather than maintaining static policies as resources scaled.

JSON protocol support (2023): In November 2023, we added support for the JSON protocol in the AWS SDK, reducing end-to-end message processing latency by up to 23% for a 5 KB payload and lowering client-side CPU and memory usage.

Amazon EventBridge Pipes console integration (2023): We added the ability to connect a queue directly to EventBridge Pipes from the SQS console, routing messages to a broad range of AWS service targets without writing custom integration code.

Extended Client Library for Python (2024): We brought the Extended Client Library, previously available for Java, to Python developers, allowing messages up to 2 GB to be sent through SQS by storing the payload in Amazon S3 and passing a reference through the queue.

FIFO in-flight message limit increase (2024): We increased the in-flight message limit for FIFO queues from 20,000 to 120,000 messages, so consumers can process significantly more messages concurrently without being constrained by the previous ceiling.

Fair queues for multi-tenant workloads (2025): We introduced fair queues to mitigate the noisy neighbor problem in multi-tenant standard queues. By including a message group ID when sending messages, customers can prevent a single tenant from delaying message delivery for others, without any changes required on the consumer side.

1 MiB maximum message payload size (2025): We increased the maximum message payload from 256 KiB to 1 MiB for both standard and FIFO queues, helping customers send larger messages without offloading data to external storage. AWS Lambda event source mapping for SQS was updated in parallel to support the new payload size.

The constant underneath the change
Despite two decades of feature additions, the fundamental use case for SQS has not shifted. Customers use it to decouple services, buffer bursts of traffic, and build systems that stay resilient when individual components fail. That same pattern now extends to AI workloads. Customers use SQS queues to buffer requests to large language models, manage inference throughput, and coordinate communication between autonomous AI agents operating as independent services. For an example of this architecture in practice, read Creating asynchronous AI agents with Amazon Bedrock.

To learn more about Amazon SQS, visit the Amazon SQS product page, review the developer guide, or explore recent updates on the AWS Blogs.

— Esra

AWS Weekly Roundup: AWS Builder Center at 1 year, Network Scanning in Security Hub, Loom for AWS, and more (July 13, 2026)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-builder-center-at-one-year-network-scanning-in-security-hub-loom-for-aws-and-more-july-13-2026/

AWS Builder Center turned one year old last week. Launched on July 9, 2025, the platform has grown from a community hub with Wishlist voting, community profiles, and a toolbox into a full ecosystem with sandbox environments, workshops, Spaces, and a Builders’ Library. To mark the anniversary, Rick Suttles published a full feature timeline covering everything shipped over the past year: AWS Capabilities by Region (1,500+ services across 37 Regions), Spaces for community-created groups, workshops with category and complexity filters, badges and streaks, article series, view counts, saved items, student status, availability notifications, sign-in with GitHub and Amazon, and sandbox environments.

Jeff Barr published a retrospective summarizing Builder Center’s first year. Since launch, 5,548 authors have published 6,448 articles with more than 10.4 million page views combined. Builders have earned 99,226 badges since the badge system launched in March 2026. Community members have submitted 565 wishes, 10 of which have shipped with another 20 on the near-term roadmap.

The top community article Building an AWS Study Buddy with MCP + Strands Agents SDK by Dineshraj Dhanapathy reached 50,000+ views. Chris Miller’s Migrating an EOL Linux Server to AWS in 8 Hours with Kiro followed at 45,000+, and Yash Aggarwal’s AIdeas: NeuroVoice – Multimodal AI for Early Screening of Neurological Diseases article reached 38,000+.

The week’s headline addition is Sandbox Environments by Rick Suttles. Sandboxes give you a free, pre-provisioned AWS account to complete a workshop exercise. Each environment is active for 8 hours, after which the account and all its resources are automatically de-provisioned. You can have one active sandbox at a time and request one per week. No personal AWS account, credit card, or manual cleanup required.

Last week’s launches
Here’s what else happened this week.

  • AWS Security Hub introduces Network Scanning – Security Hub introduced Network Scanning, a capability that identifies resources in your environment that are reachable from the public internet. Network Scanning probes your resources from the internet to detect actual reachability, complementing the existing network reachability findings in Security Hub that identify configurations that could make a resource reachable. It discovers public IP addresses, virtual machines, and load balancers across your AWS and Azure environments, identifies reachable ports, and determines what services are running behind them. Each reachable port generates a Security Hub finding with evidence of the port and service discovered. Security Hub Exposures then automatically correlates these findings with other findings and resource configurations to determine broader risk. Existing customers can enable Network Scanning in individual accounts and Regions, or across an organization through a configuration policy. For new customers, Network Scanning is on by default. It is included with Security Hub Essentials at no additional cost.
  • Security Hub also extends unified security management to Microsoft Azure – Security Hub now monitors Microsoft Azure resources, providing unified posture management, vulnerability management, and security response across both clouds. It automatically discovers Azure VMs, container images, Function Apps, and identities, and evaluates them for misconfigurations, internet exposure, and software vulnerabilities. AWS and Azure findings appear in the same prioritized view with the same formats and automation workflows.
  • Amazon SageMaker Studio integrates with Hugging Face for one-click model deployment and customization – You can now go from discovering a model on Hugging Face to working with it in SageMaker Studio in a single click. Select any supported model on Hugging Face and choose “Customize on SageMaker AI” or “Deploy on SageMaker AI” to land directly on the corresponding workflow page with the model pre-loaded. New customers receive a Studio environment created in seconds with pre-configured permissions for serverless model customization (including fine-tuning with custom reward functions for reinforcement learning), model evaluation, and deployment to SageMaker or Bedrock endpoints. Verified customers receive default GPU access to G5, G6, and G4dn instances without requesting quota increases, and quota utilization is visible directly inside the Studio environment.
  • Amazon EKS Auto Mode and Amazon ECS Managed Instances reduce GPU management fees by up to 60% – Beginning July 1, 2026, EKS Auto Mode and ECS Managed Instances reduce management fees for accelerated instance types: G-series fees are down 35%, and P-series and AWS Trainium fees are down 60%. The reductions apply automatically to existing clusters and require no action from customers. Both services include capabilities built for accelerated workloads. EKS Auto Mode provides automatic parallel image pulling on GPU instances with local NVMe storage and accelerator-aware node repair. ECS Managed Instances provides GPU metrics through Amazon CloudWatch Container Insights and automatic health monitoring for GPU hardware failures.
  • Amazon Aurora DSQL change data capture (CDC) is now generally available – Aurora DSQL CDC streams the results of insert, update, and delete operations as change events to Amazon Kinesis Data Streams. You can use it to synchronize data across microservices, trigger Lambda functions, or deliver changes to S3, Redshift, and OpenSearch Service through Amazon Data Firehose. CDC streaming is designed to have zero impact on database workload performance and requires no infrastructure to manage.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts you may find useful:

  • Building secure AI agents at scale: Introducing Loom for AWS – Loom is an open-source enterprise platform for building agents with AWS Strands Agents and deploying them on Amazon Bedrock AgentCore Runtime. It provides a unified management UI and backend API with identity provider integration, scope-based authorization, multi-persona navigation, and full lifecycle management for agents, memory, MCP servers, and agent-to-agent integrations. Loom enforces automated resource tagging for cost attribution, implements RBAC and ABAC for multi-tenant security, uses paved-path blueprints for agent deployments, manages identity propagation through delegated actor chains, integrates with AWS Agent Registry for discovery and governance, and supports human-in-the-loop review before sensitive actions. The project is available in AWS Labs on GitHub.
  • Introducing Claude apps gateway for AWS – The Claude apps gateway is a self-hosted control plane that gives organizations centralized control over access, cost, and policy for Claude Code and Claude Desktop. It connects to any OIDC-compliant identity provider, enforces managed settings on every request, routes inference to Amazon Bedrock or Claude Platform on AWS, and supports per-user and per-group spend caps. The gateway runs as a stateless container in your private network, backed by a PostgreSQL database for short-lived sign-in state. No long-lived secrets are stored on developer machines. Deploy it through Amazon Bedrock to keep data within the AWS security boundary, or through Claude Platform on AWS for the native Claude platform experience.
  • Introducing OAuth support for AWS MCP Server – You can now connect agents to the AWS MCP Server using browser-based OAuth with the same credentials you use for the AWS Console or CLI. The new sign-in path supports IAM federation, AWS IAM Identity Center, and root or IAM users. AWS Sign-In issues short-lived access tokens and refresh tokens, with automatic token management so developers stay authenticated across restarts. For headless use cases, a non-interactive flow lets applications with existing AWS credentials obtain OAuth access tokens through the create-oauth2-token-with-iam API. New governance controls include OAuth-specific IAM condition keys, token introspection and revocation, dynamic client registration, and CloudTrail audit elements.

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

Visit the AWS Builder Center to meet other builders, contribute solutions, and find resources that help you keep building.

Wishing everyone a restful and enjoyable summer. Whether you’re building, learning, or recharging, I hope you find time for all three. I’ll be heading to Scandinavia for a few weeks to trade the heat for some cooler weather and longer evenings. Come back next week for more news!

— Esra

Upgrade Amazon EKS clusters with confidence using Kubernetes version rollbacks

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/upgrade-amazon-eks-clusters-with-confidence-using-kubernetes-version-rollbacks/

Upgrading a Kubernetes control plane has long been a one way door. Open source Kubernetes doesn’t support control plane rollback, so once you upgrade, there’s no going back. The community is making real progress here, and KEP-4330 introduces emulated versions to ease rollback. But in practice this constraint has pushed organizations to build elaborate compensating mechanisms like bake periods, stagger groups, automated sign offs, and months long upgrade cycles. With Kubernetes releasing three minor versions per year, teams managing hundreds of clusters, especially in regulated environments, often delay upgrades entirely because they aren’t confident they can recover if something goes wrong. The result is clusters stuck on older versions, missing security patches, and eventually running up against extended support timelines.

Today, we’re announcing Kubernetes version rollbacks for Amazon Elastic Kubernetes Service (Amazon EKS), a new feature that gives cluster administrators a safety net when performing cluster upgrades. With version rollbacks, you can reverse a Kubernetes version upgrade within seven days if you encounter issues after upgrading, returning your cluster to its previous working state.

Where approaches like emulated versions keep a cluster in a transitional holding state, EKS version rollback returns your cluster to a fully validated previous version that ran in production, not an emulation of it. Now, if you upgrade a cluster from, say, Kubernetes 1.34 to 1.35 and discover a compatibility issue, you can roll back to 1.34 within seven days. There’s no need to rebuild your cluster or scramble to troubleshoot under pressure. Think of it as an undo button for Kubernetes version upgrades.

The feature supports rolling back one minor version at a time, matching the same incremental approach EKS uses for upgrades. And to help you roll back safely, EKS automatically evaluates your cluster’s rollback readiness through cluster insights, flagging items like node version compatibility or add-on dependencies before you proceed. If you’ve already assessed the situation and want to move quickly, you can use the --force flag to bypass those checks. The above applies to all EKS clusters, whether you manage your own nodes or let AWS handle them. But for customers who have embraced fully managed infrastructure, rollback goes a step further.

Rollback for EKS Auto Mode
EKS Auto Mode gives you one click deployment of production ready Kubernetes clusters, automating compute, networking, and storage management so you can focus on your applications rather than infrastructure. EKS Auto Mode introduces additional considerations for version rollbacks because both the control plane and managed nodes need to be rolled back together. Since node rollbacks respect your pod disruption budgets, the process can take time depending on your configuration.

To give you control over this process, we’ve introduced a cancel API that lets you stop a node rollback at any point. If you decide the rollback is taking too long or you want to change your approach, you can cancel and adjust your disruption budgets to accelerate things, or choose a different path forward.

By default, EKS never bypasses your disruption budgets during a rollback because we prioritize workload stability. You can always choose to modify or remove disruption budgets yourself to speed up the process if needed.

Let’s try it out
To try version rollbacks, I navigated to the Amazon EKS console and selected one of my clusters that I had recently upgraded.

From the cluster’s configuration page, I can see the option to initiate a version rollback, along with information about my current rollback window.

Before initiating the rollback, I reviewed the rollback insights to check for any potential issues. The insights showed me the status of my nodes and flagged anything I should address before proceeding.

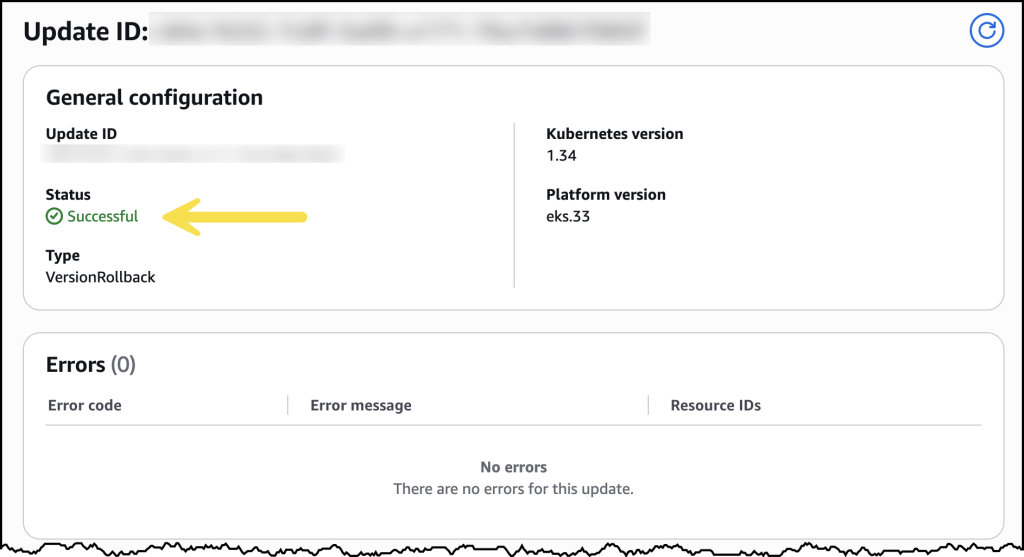
After confirming, the rollback began. My cluster remained functional throughout the process. The control plane rollback took about 20 minutes, similar to a standard upgrade. For my EKS Auto Mode cluster, the nodes rolled back gracefully according to my disruption budget settings.

Once complete, my cluster was back on the previous Kubernetes version, running as expected.

Now available
Kubernetes version rollbacks for Amazon EKS are available today at no additional cost in all commercial AWS Regions where Amazon EKS is available. You pay only for the standard EKS and compute costs you would normally incur. There are no extra charges for using the rollback capability.

Control plane rollbacks are available for all EKS clusters, and node rollbacks are available for clusters running EKS Auto Mode. Version rollbacks support clusters running Kubernetes versions available in EKS standard support and extended support.

To get started, visit the Amazon EKS documentation or try it out directly in the Amazon EKS console.

Accelerate your infrastructure deployments by up to 4x with AWS CloudFormation Express mode

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/accelerate-your-infrastructure-deployments-by-up-to-4x-with-aws-cloudformation-express-mode/

Today, we’re announcing AWS CloudFormation Express mode, a new deployment mode that accelerates deployments for developers and AI tools iterating on infrastructure. Express mode accelerates deployments by completing when CloudFormation confirms resource configuration is applied, rather than waiting for extended stabilization checks. This reduces deployment time by up to 4 times for iterative development workflows and production scenarios.

How it works
Every CloudFormation deployment performs stabilization checks after resource configuration is applied. These checks serve an important purpose when you need to confirm resources can serve traffic before shifting load.

However, many workflows do not require full stabilization to proceed. Express mode benefits two primary use cases: iterative development workflows and production scenarios where you are comfortable with eventual stabilization. These use cases include iterating on infrastructure configurations during development, testing individual components of your application, and AI-assisted infrastructure development that benefits from sub-minute feedback loops.

With Express mode, CloudFormation completes deployments when resource configuration is applied, without waiting for stabilization checks. Resources continue becoming operational in the background. CloudFormation automatically retries dependent resources that encounter transient failures during provisioning within the same stack, without requiring any customer intervention. This built-in resilience handles timing issues between resources as they stabilize. Express mode changes when the deployment completes, not how resources are provisioned.

For example, when I create an Amazon Simple Queue Service (SQS) queue with a dead letter queue (DLQ), Standard mode takes 64 seconds, but Express mode completes in up to 10 seconds. In the case of deleting an AWS Lambda function with network interface attachment, Standard mode takes 20–30 minutes, but Express mode completes in up to 10 seconds based on my benchmarking test.

Get started with CloudFormation Express mode
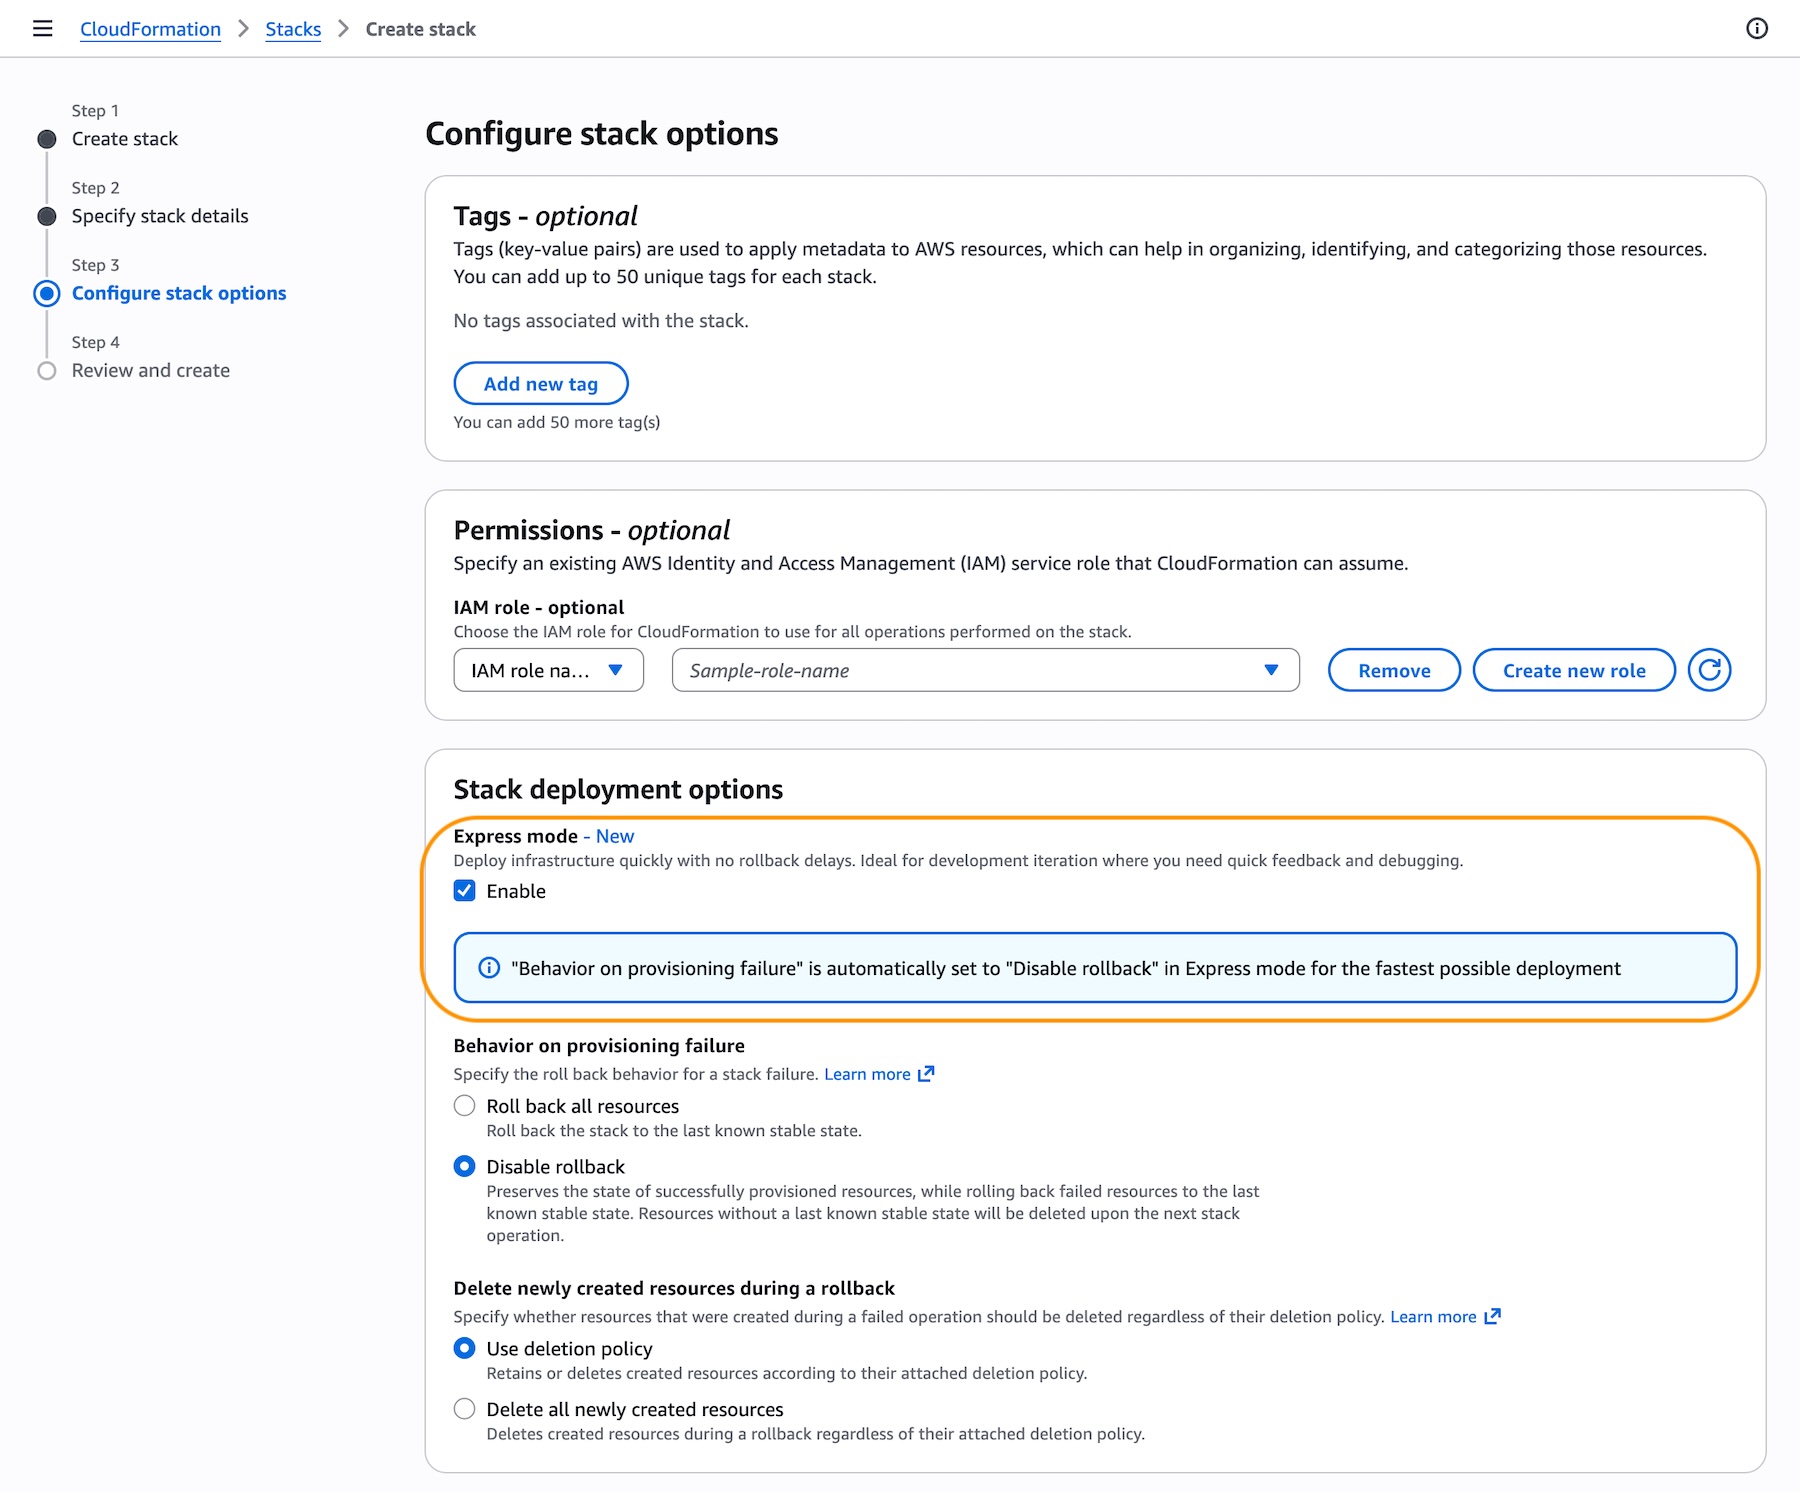
When you create a CloudFormation stack in the AWS Management Console, choose Enable in the Express mode under Stack deployment options.

You can also use AWS Command Line Interface (AWS CLI), AWS SDKs, or IaC tools like AWS Cloud Development Kit (CDK), and AI tools such as Kiro.

Activate Express mode by setting the --deployment-config parameter to EXPRESS when creating, updating, or deleting stacks. No template changes are required. Express mode disables rollback by default for the fastest iteration experience. To re-enable rollback, set disableRollback to false in the deployment-config for production environments, or implement monitoring/cleanup mechanisms for failed deployments.

aws cloudformation create-stack \ 
   --stack-name my-app \ 
   --template-body file://template.yaml \ 
   --deployment-config '{"mode": "EXPRESS", "disableRollback": true}' \

For example, use the Express mode when you build infrastructure incrementally, adding resources one at a time. Ensure your IAM role templates follow the principle of least privilege.

# Iteration 1: Deploy IAM role
aws cloudformation create-stack \
--stack-name my-microservice \
--template-body file://iteration1-iam.yaml \
--deployment-config '{"mode": "EXPRESS"}' \
--capabilities CAPABILITY_IAM
--role-arn arn:aws:iam::123456789012:role/CloudFormationDeployRole

# Iteration 2: Add Lambda function
aws cloudformation update-stack \
--stack-name my-microservice \
--template-body file://iteration2-lambda.yaml \
--deployment-config '{"mode": "EXPRESS"}' \
--capabilities CAPABILITY_IAM
--role-arn arn:aws:iam::123456789012:role/CloudFormationDeployRole

# Iteration 3: Add SQS queue and event source mapping
aws cloudformation update-stack \
--stack-name my-microservice \
--template-body file://iteration3-sqs.yaml \
--deployment-config '{"mode": "EXPRESS"}' \
--capabilities CAPABILITY_IAM
--role-arn arn:aws:iam::123456789012:role/CloudFormationDeployRole

For AWS CDK, activate Express mode with the cdk deploy --express command when you deploy your CDK stack. This command retrieves your generated CloudFormation template and deploys it through the CloudFormation Express mode, which provisions your resources as part of a CloudFormation stack.

Express mode works with all existing CloudFormation templates and supports all CloudFormation features including change sets and nested stacks. When you enable Express mode on a parent stack, all nested stacks also use Express mode. If you need resources to be fully operational before proceeding with traffic or testing, continue using the default deployment behavior, which performs stabilization checks before completing.

Now available
AWS CloudFormation Express mode is available today in all AWS commercial Regions at no additional cost. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this new feature, try using the AWS MCP Server and plugins with your preferred AI tool. To learn more, visit the CloudFormation documentation.

Start accelerating your deployments today, and send feedback to AWS re:Post for AWS CloudFormation or through your usual AWS Support contacts.
— Channy

Amazon EC2 C9g and C9gd instances powered by AWS Graviton5 processors are now available

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-ec2-c9g-and-c9gd-instances-powered-by-aws-graviton5-processors-are-now-available/

When you run compute-intensive workloads like real-time analytics, batch processing, video encoding, scientific modeling, or CPU-based machine learning inference, every percentage point of performance matters. You need instances that deliver higher throughput per vCPU, faster memory access, and more network bandwidth, all while keeping your costs in check.

Today I am happy to announce the general availability of Amazon Elastic Compute Cloud (Amazon EC2) C9g and C9gd instances, powered by AWS Graviton5 processors. C9g instances are compute-optimized and deliver up to 25% higher performance per vCPU compared to previous-generation C8g instances. They feature the fastest memory of any processor instance in the cloud, with DDR5 8800MT/s DIMMs, 5x more L3 cache, and up to 3x higher packet-processing performance compared to Graviton4-based instances. The faster memory and larger caches mean your workloads spend less time waiting on data, translating into higher throughput for in-memory analytics, faster agentic loops, and more responsive real-time applications.

C9g instances are ideal for batch jobs, video encoding pipelines, or distributed analytics that can utilize Amazon Elastic Block Store (Amazon EBS) for storage. It is also a natural fit for agentic AI workloads, where concurrent environments and CPU-bound reasoning steps benefit from Graviton5’s higher core count and larger caches. As AI shifts from answering questions to taking actions, running code, and orchestrating multi-step tasks, the demand for CPU compute is growing, and C9g instances are built for this shift.

Some workloads also need fast local storage alongside that compute power. Choose C9gd when your application benefits from high-speed, low-latency local NVMe SSD storage, for example scratch space during HPC simulations, temporary caches for ML inference, or local buffers for ad-serving engines.

Graviton5-based instances with NVMe instance store volumes also support detailed performance statistics, providing high-resolution I/O metrics, including latency histograms broken down by I/O size, up to 1-second granularity and accessible via Amazon CloudWatch or nvme-cli at no additional cost.

C9g and C9gd instances at a glance
C9g and C9gd instances are available in 11 sizes ranging from medium to 48xlarge, plus a bare metal option. They offer up to 15% higher network bandwidth and 20% higher EBS bandwidth on average across sizes compared to the previous generation, with the largest 48xlarge size delivering up to 100 Gbps of network bandwidth and up to 72 Gbps of EBS bandwidth, a 2x increase.

C9g vCPUs Memory
(GiB)
Network Bandwidth
(Gbps)
EBS Bandwidth
(Gbps)
medium 1 2 Up to 15 Up to 12
large 2 4 Up to 15 Up to 12
xlarge 4 8 Up to 15 Up to 12
2xlarge 8 16 Up to 17 Up to 12
4xlarge 16 32 Up to 17 Up to 12
8xlarge 32 64 17 12
12xlarge 48 96 25 18
16xlarge 64 128 34 24
24xlarge 96 192 50 36
48xlarge 192 384 100 72
metal-48xl 192 384 100 72

C9gd instances add local NVMe SSD storage with up to 30% higher storage performance compared to previous-generation local storage instances.

C9gd vCPUs Memory
(GiB)
Instance Storage
(GB)
Network Bandwidth
(Gbps)
EBS Bandwidth
(Gbps)
medium 1 2 1 x 59 Up to 15 Up to 12
large 2 4 1 x 118 Up to 15 Up to 12
xlarge 4 8 1 x 237 Up to 15 Up to 12
2xlarge 8 16 1 x 474 Up to 17 Up to 12
4xlarge 16 32 1 x 950 Up to 17 Up to 12
8xlarge 32 64 1 x 1900 17 12
12xlarge 48 96 3 x 950 25 18
16xlarge 64 128 1 x 3800 34 24
24xlarge 96 192 3 x 1900 50 36
48xlarge 192 384 3 x 3800 100 72
metal-48xl 192 384 3 x 3800 100 72

Both families are well-suited for high-performance computing (HPC), batch processing, gaming, video encoding, scientific modeling, distributed analytics, CPU-based machine learning inference, and ad serving.

Here are some additional capabilities:

  • Instance Bandwidth Configuration (IBC) lets you adjust the allocation of bandwidth between Amazon EBS and Amazon VPC networking by up to 25%, helping you optimize performance for workloads with specific bandwidth requirements such as databases and caching.
  • ENA Express support for enhanced networking.
  • Up to 128 EBS volumes can be attached to virtual instances.
  • Support for Savings Plans, On-Demand, Spot Instances, Dedicated Instances, and Dedicated Hosts.

Nitro Isolation Engine
C9g and C9gd instances are the first compute optimized Amazon EC2 instances to feature the AWS Nitro Isolation Engine, a new capability of the AWS Nitro System. The Nitro Isolation Engine is a purpose-built component of the Nitro Hypervisor, implemented in Rust, that enforces isolation between virtual machines. It mediates all access to VM memory, CPU register state, and I/O devices through a minimal set of APIs.

To learn more about the Nitro Isolation Engine, visit the blog post. For details on the formal verification results, including scope and assumptions, see our technical white paper.

Now available
Amazon EC2 C9g and C9gd instances are now available in US East (Ohio, N. Virginia), US West (Oregon), and Europe (Frankfurt). Additional regions will follow.

You can launch C9g and C9gd instances today using the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs. For pricing information, visit the Amazon EC2 Pricing page.

To learn more, visit the Amazon EC2 C9g and C9gd instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.
— seb

Automate public TLS certificate issuance with ACME support in AWS Certificate Manager

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/automate-public-tls-certificate-issuance-with-acme-support-in-aws-certificate-manager/

If you manage TLS certificates for your applications, you know the challenge: certificates expire, and when they do, your customers see errors or your service goes down. As certificate validity periods get shorter (the Certification Authority (CA)/Browser Forum mandates reduced maximum validity to 100 days starting March 2027, and to 47 days by 2029), manual renewal processes become untenable. You need automation.

Automatic Certificate Management Environment (ACME) is an open protocol for requesting, renewing, and revoking TLS certificates without human intervention. It’s the same protocol behind Let’s Encrypt, and it’s supported by dozens of clients across every platform.

Today we’re announcing ACME support for public certificates in AWS Certificate Manager (ACM). ACM now provides a fully managed ACME server endpoint that works with any ACMEv2-compatible client, such as Certbot, cert-manager for Kubernetes, acme.sh, or any other client you already use. You can issue public TLS certificates from Amazon Trust Services through the standard ACME protocol.

Before today, if you wanted automated certificate management using the ACME protocol, you relied on external certificate authorities alongside ACM, leading to a fragmented visibility experience. Some certificates lived in ACM, others were managed externally with no central dashboard. PKI administrators had limited ability to control who could request certificates or which domains were allowed.

With ACME support in ACM, you can now set up one or more managed ACME endpoint that allows you to centrally manage and monitor ACME certificate usage across your organization.

As a PKI administrator, you get centralized controls that go beyond basic certificate issuance. You can bind IAM roles to ACME accounts for fine-grained access control over which domains each client can request. You can define domain scopes at the endpoint level to enforce organization-wide policies. And you get centralized monitoring and visibility in the same place: AWS CloudTrail logs every certificate request for auditability, Amazon CloudWatch tracks operational metrics, and ACM sends expiry notifications when certificates are approaching renewal. Using ACM, your PKI team can search all certificates, whether issued through the ACM console, an API call, or ACME.

How it works
To get started, you first set up a dedicated ACME endpoint, configure authorization controls using External Account Binding (EAB), validate which domains the endpoint can issue certificates for, and point your existing ACME clients to the new endpoint.

The domain validation step is important: it separates who can set up certificate issuance from who can request certificates. The PKI administrator validates domains once at the endpoint level, using DNS credentials that stay with the admin. Application owners who need certificates never touch DNS. They register with an EAB credential, and the endpoint enforces which domains and scopes they’re allowed to request. This means you can distribute certificate automation broadly across your organization without distributing DNS keys along with it.

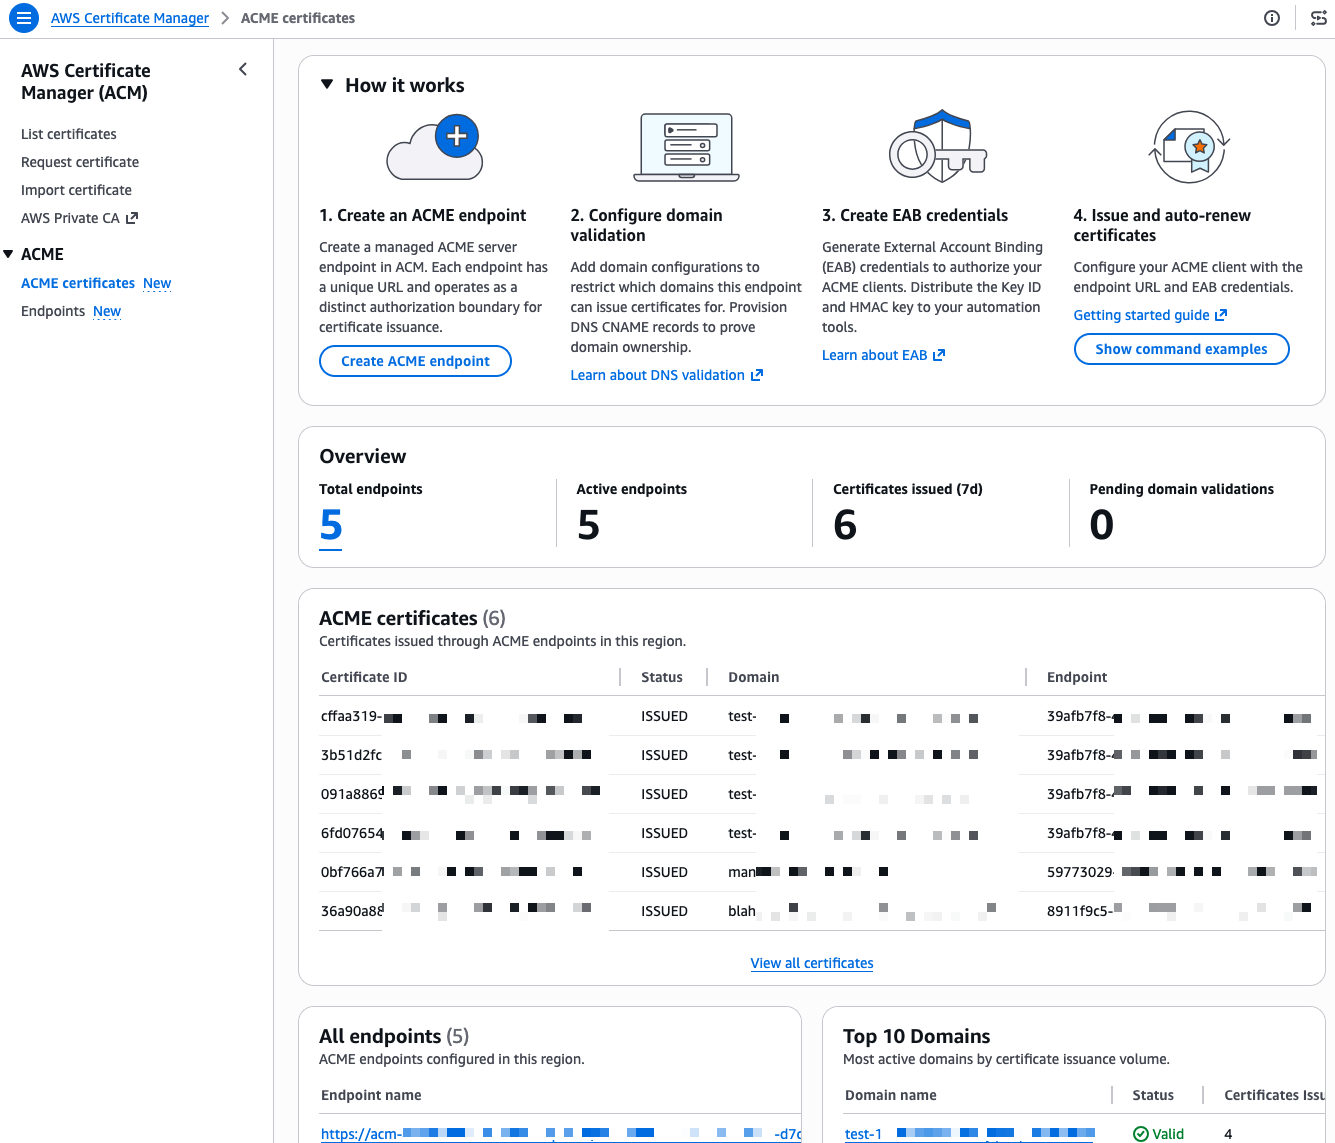
I start this demo from the ACME certificates page in the AWS Certificate Manager console.

ACME Console

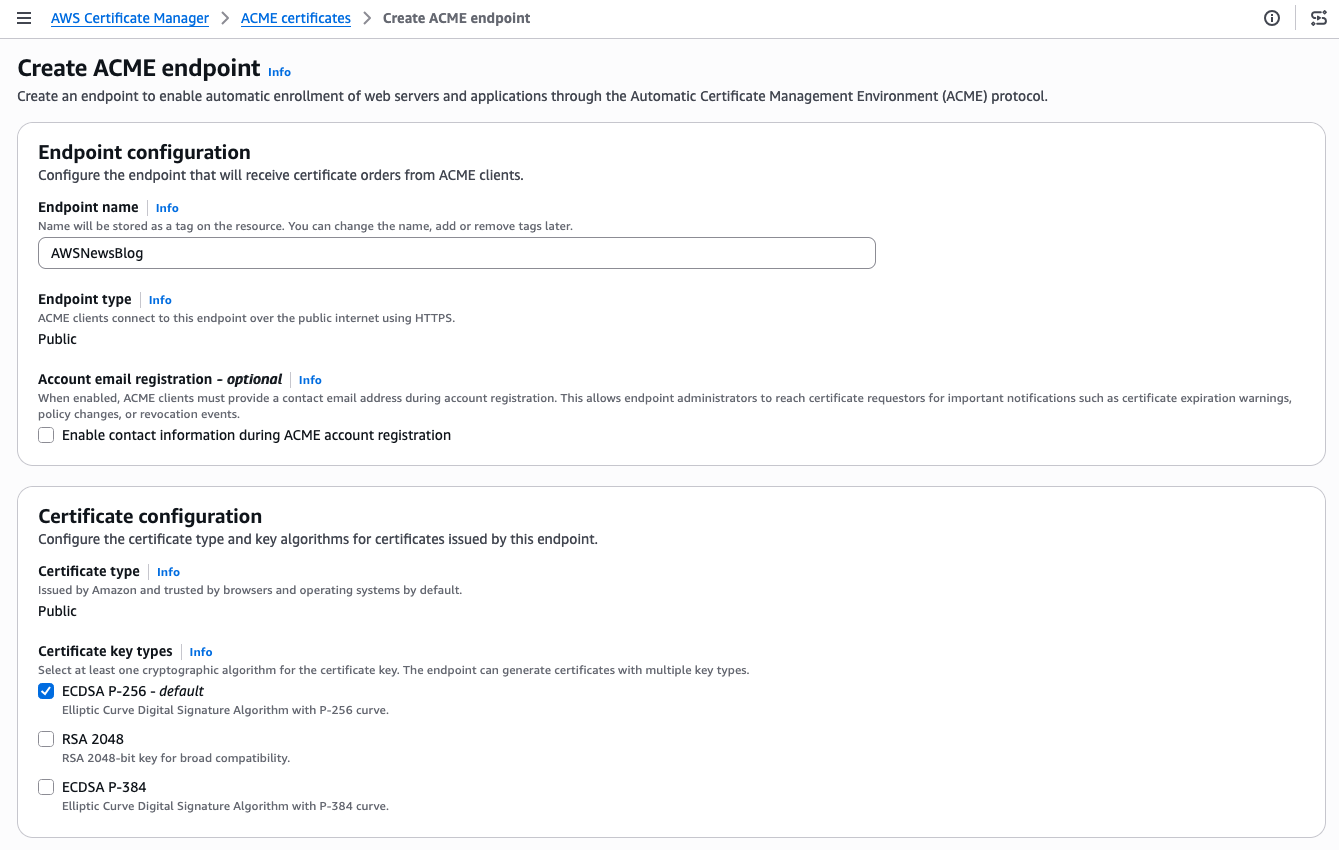
I already have a few endpoints and certificates in this account, I walk you through creating a new one from scratch. First, I select Create ACME endpoint.

ACME - Ceeate endpoint 1

I give my endpoint a name. The Endpoint type is Public. ACME clients will connect over the public internet. The Certificate type is Public. The certificate will be issued by Amazon Trust Services and trusted by browsers and operating systems by default. For the certificate key type, I keep the default ECDSA P-256. RSA 2048 and ECDSA P-384 are also available if your clients require them.

ACME - Ceeate endpoint 2

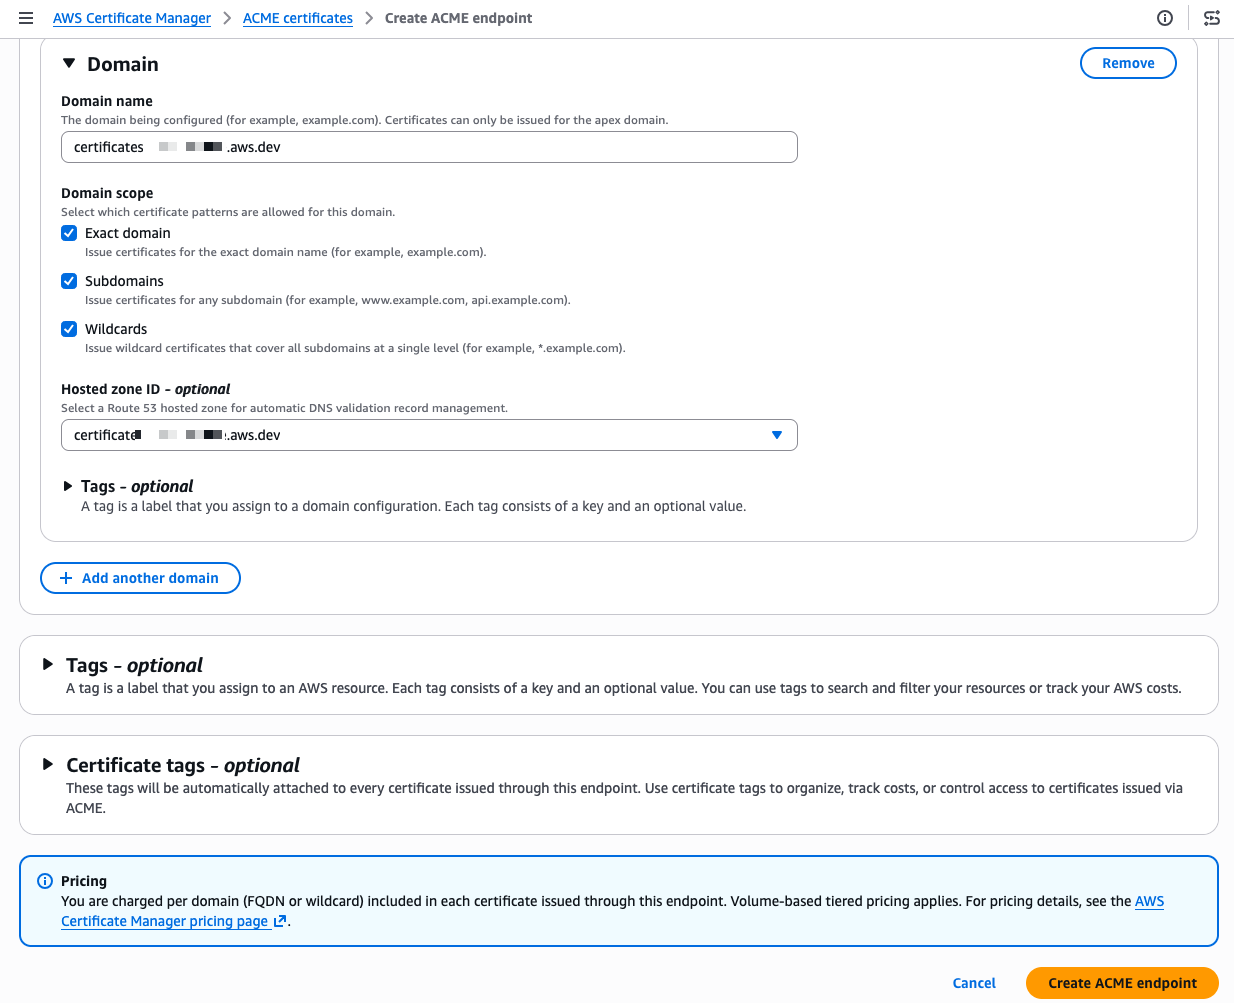
Scrolling down, I configure the domain. I enter my domain name and select the domain scope. The scope controls exactly what certificate patterns your ACME clients are allowed to request for this domain. If I check only Exact domain, clients can only request certificates for that specific domain name. Adding Subdomains allows certificates for any subdomain (for example, api.example.com or dev.example.com). Adding Wildcards allows wildcard certificates (*.example.com). By leaving a scope unchecked, you prevent any client using this endpoint from requesting that type of certificate, even if their ACME request is otherwise valid. For a production endpoint, you might enable only Exact domain and Subdomains while leaving Wildcards unchecked to enforce a stricter security posture.

I also select my Amazon Route 53 hosted zone from the drop down menu. ACM then automatically creates the DNS CNAME records needed for domain validation, so I don’t have to do it manually. When my domain is hosted outside of Route 53, I manually create the provided CNAME record at my DNS provider instead. This is a meaningful difference from typical ACME setups where each client handles its own domain verification independently.

These centralized controls give PKI administrators a single place to authenticate domains, restrict which certificate types (ECDSA or RSA) clients can request, and further limit wildcard issuance. Having these governance capabilities built in means you don’t need to purchase a separate certificate lifecycle management product or invest in building a custom policy layer yourself, both of which come at significant cost and operational overhead.

I select Create ACME endpoint

ACME - DNS configuration

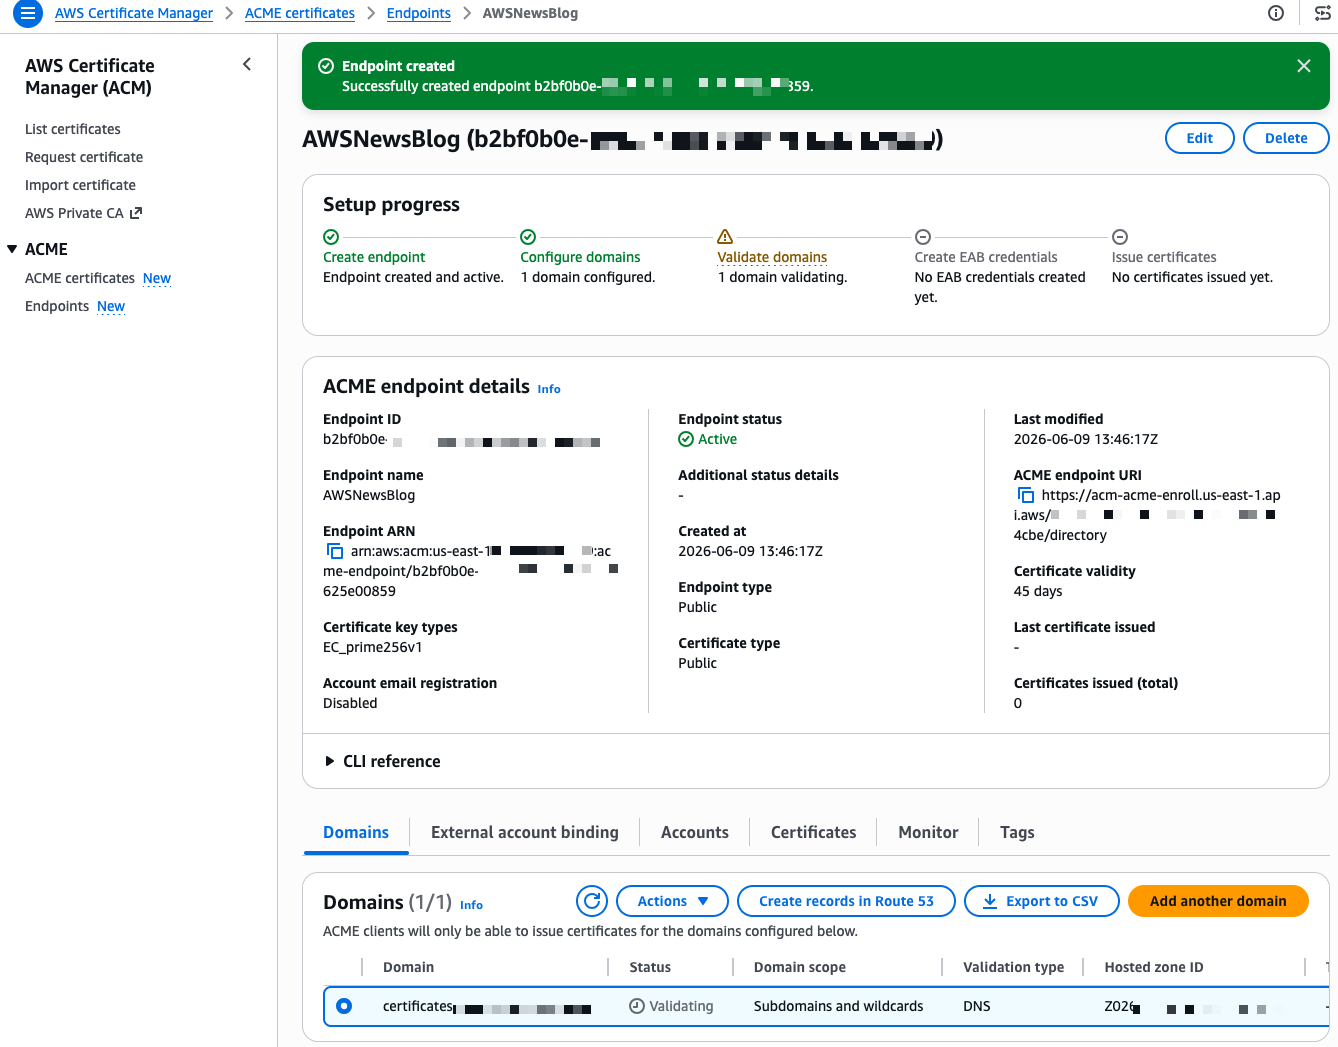
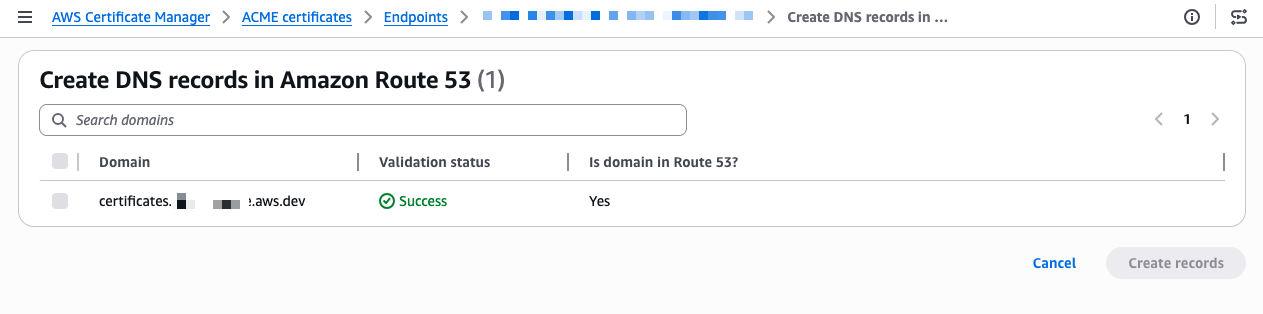
After a few seconds, the endpoint is created. The console shows a Setup progress tracker with the next steps. My domain shows a “Validating” status. The validation method is DNS validation, where ACM verifies that you control the domain by checking for a specific CNAME record. Because I selected my Route 53 hosted zone during creation, I select Create records in Route 53 to let ACM handle the DNS validation automatically.

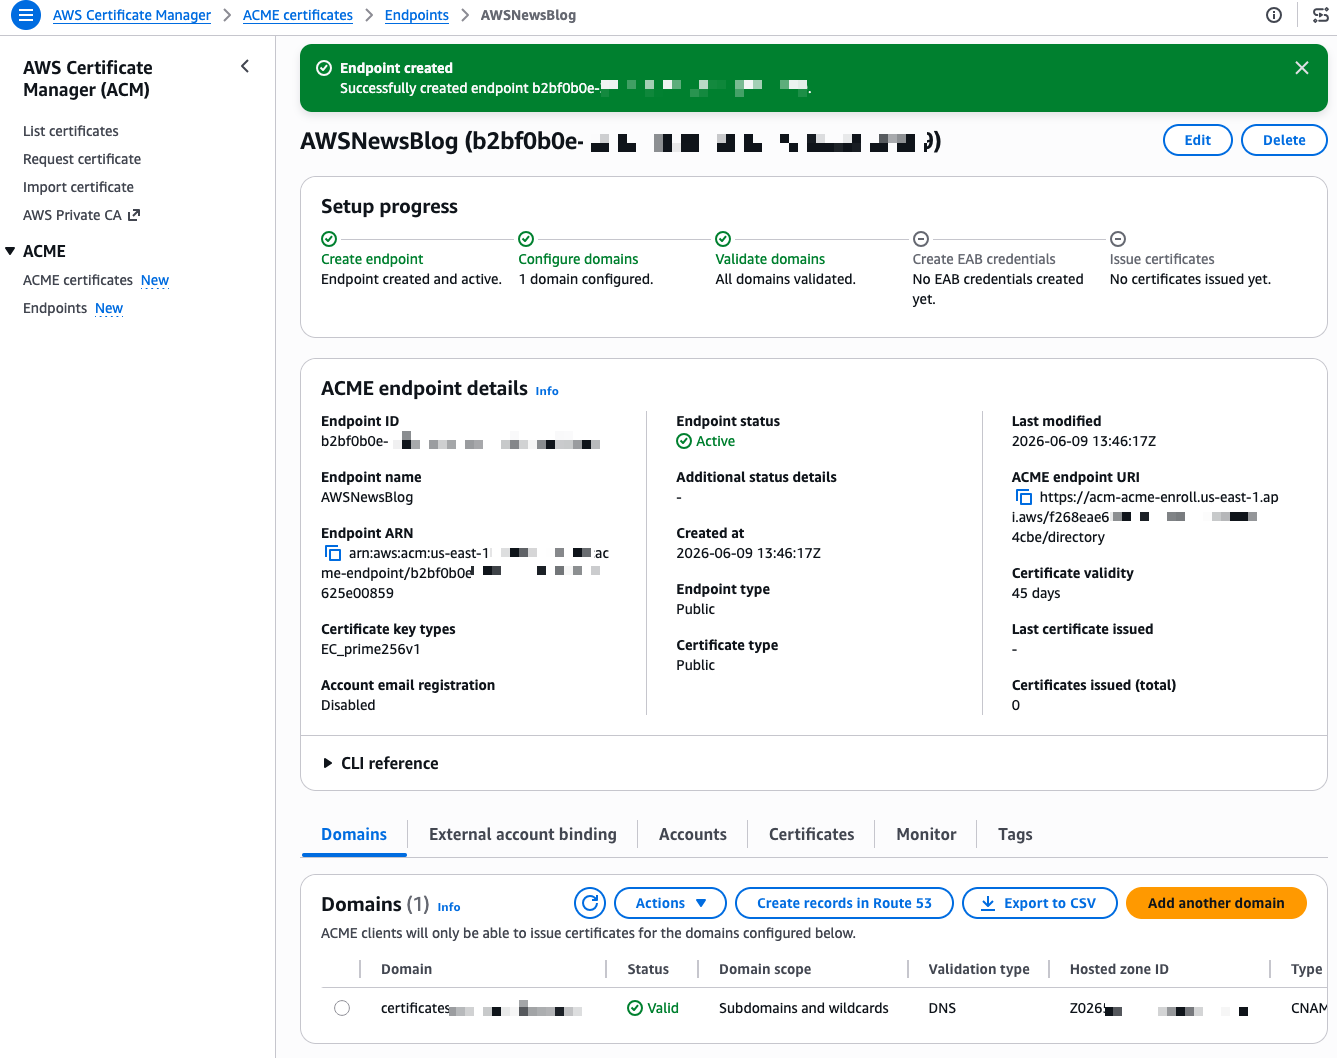
ACME - DNS successThe validation completes in a few seconds and the status changes to Success.

ACME - External Account Binding 1

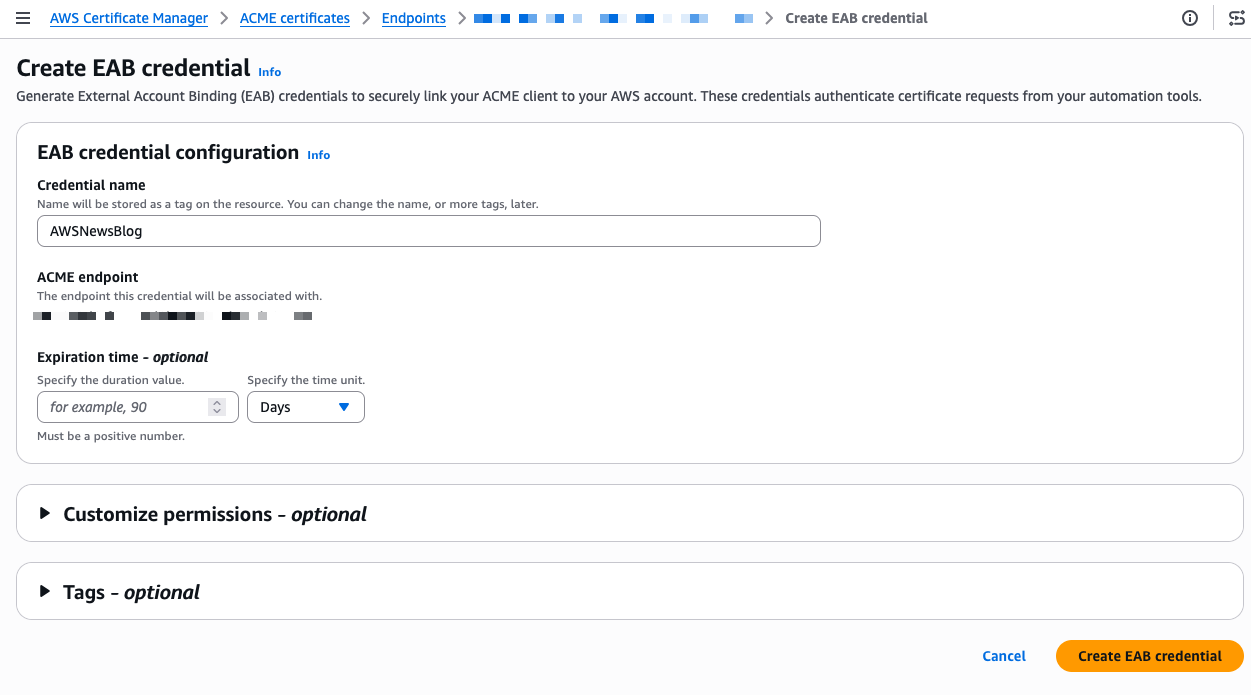
Now I need to create External Account Binding (EAB) credentials. EAB credentials are a key identifier and HMAC key pair that lets your ACME client register an account with the ACME server. Once registered, the client generates its own asymmetric key pair, which is then used to authenticate all subsequent certificate requests. On the endpoint details page, I select the External account binding tab, then select Create EAB. I give the credential a name and optionally set an expiration time, ideally no longer than needed to complete client registration.

ACME - External Account Binding 2

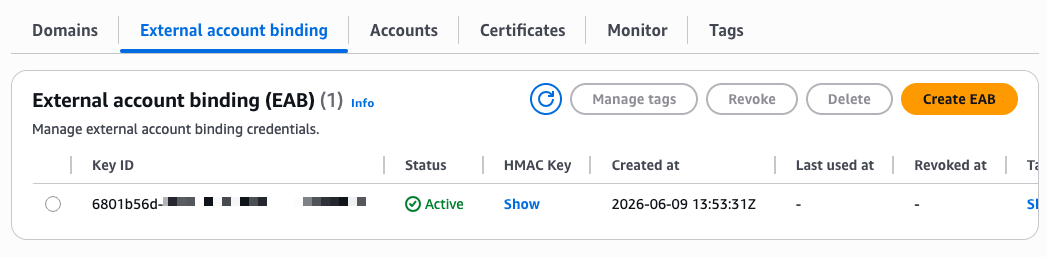
ACME - end of configuration - show key

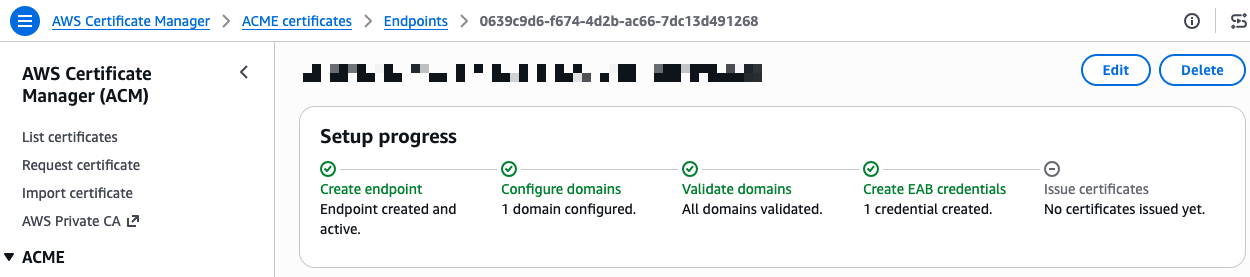
After I select Create EAB credential, the console shows the Key ID and HMAC Key. I note these values because I need them to configure my ACME client. The setup progress now shows four green checkmarks.

ACME - end of configuration - success

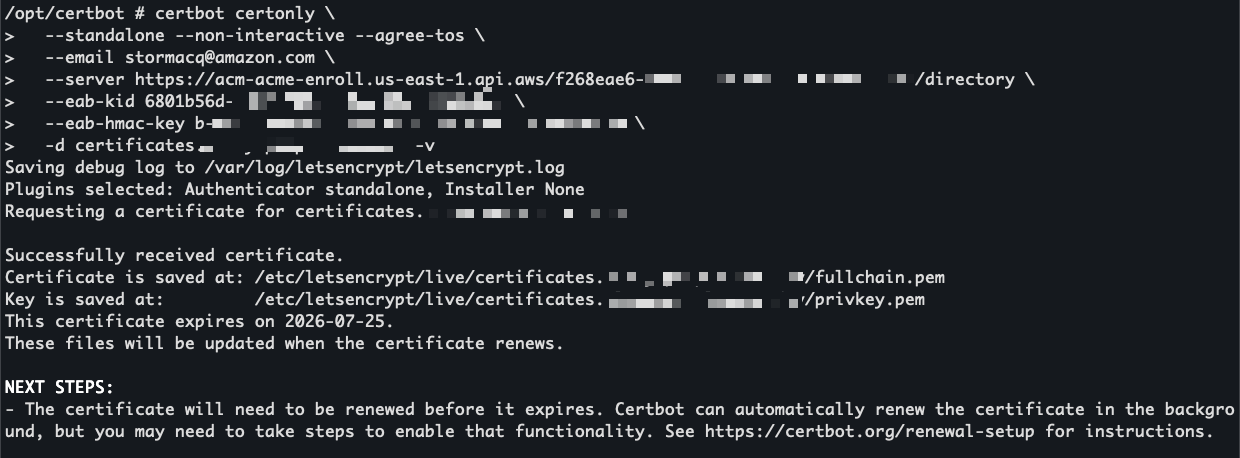
I’m ready to request a certificate. On the endpoint details page, I expand the CLI reference section. The console provides ready-to-use command examples for both Certbot and acme.sh. I copy the Certbot command and run it inside a container using the certbot/certbot image.

certbot certonly --standalone --non-interactive --agree-tos \
    --email <EMAIL> \
    --server https://acm-acme-enroll.us-east-1.api.aws/<ENDPOINT_ID>/directory \
    --eab-kid <EAB_KID> \
    --eab-hmac-key <EAB_HMAC_KEY> \
    --issuance-timeout <ISSUANCE_TIMEOUT> \
    -d <DOMAIN>

I replace the placeholders with my endpoint URL, EAB credentials, and domain name. The --eab-kid and --eab-hmac-key arguments are how Certbot registers with your ACME endpoint using the External Account Binding credentials I generated earlier. Each ACME client has its own syntax for this step, so check your client’s documentation for the exact flags.

Certbot contacts the ACME endpoint and returns a valid certificate signed by Amazon Trust Services.

Certbot to obtain a certificate through ACME

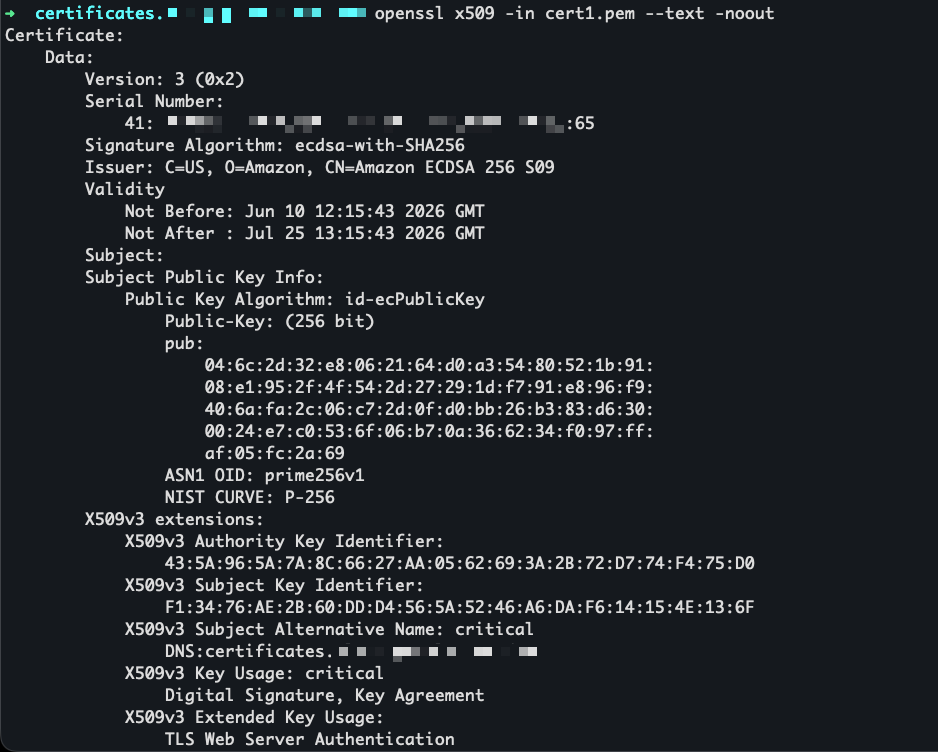
I use openssl to view the certificate before installing it.

openssl to view the certificate

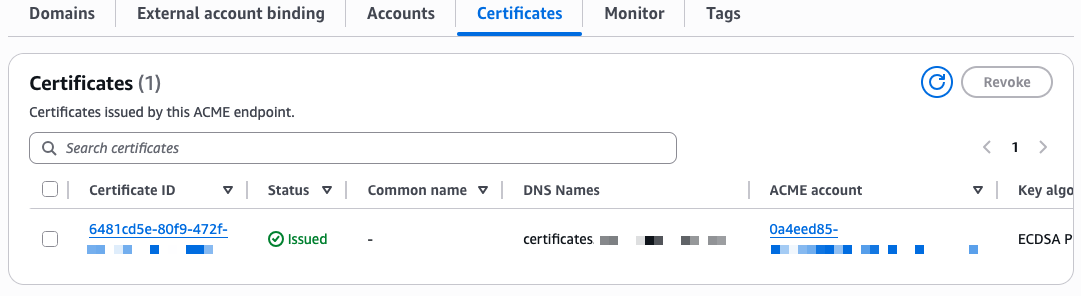
The certificate is now visible in the ACM console under the ACME certificates tab, alongside any certificates issued through the console or API.

Certoficate view in the ACME console

Availability and pricing
ACME support in AWS Certificate Manager is available today in all commercial AWS Regions and will be available in AWS GovCloud (US), the China Regions, and the AWS European Sovereign Cloud partitions at a later date.

Pricing is per domain included in each certificate at the time of issuance, with a different price for fully qualified domain names and wildcards. Volume tiers are calculated based on total domain occurrences across all certificates issued per month in your AWS account. For details, see the ACM pricing page.

To get started, visit the ACM section on the AWS console or read the documentation.

— seb

Run isolated sandboxes with full lifecycle control: AWS Lambda introduces MicroVMs

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/run-isolated-sandboxes-with-full-lifecycle-control-aws-lambda-introduces-microvms/

Today, we are announcing AWS Lambda MicroVMs, a new serverless compute primitive within AWS Lambda that lets you run code generated by users or AI in isolated, stateful execution environments. You get virtual machine level isolation, near-instant launch and resume, and direct control over environment lifecycle and state, all without managing infrastructure or building expertise in complex virtualization technologies. Lambda MicroVMs are powered by Firecracker, the same lightweight virtualization technology that has powered over 15 trillions of monthly Lambda function invocations.

Why customers need this
Over the past few years a new class of multi-tenant applications has emerged that all share the need to hand each end user their own dedicated execution environment in which to safely run code that the application developer did not write. AI coding assistants, interactive code environments, data analytics platforms, vulnerability scanners, and game servers that run user-supplied scripts all fit this pattern. Building that capability today means making a difficult choice. Virtual machines deliver strong isolation but take minutes to start. Containers launch in seconds, yet their shared-kernel architecture requires significant custom hardening to safely contain untrusted code. Functions as a service are optimized for event-driven, request-response workloads, but are not designed for long-running interactive sessions that need to retain environment state across user interactions. That leaves developers either accepting tradeoffs between performance and isolation, or investing significant engineering resources to build and operate custom virtualization infrastructure to achieve isolated execution while delivering low-latency experiences to end-users. This presents an effort that demands deep expertise and pulls engineering time away from the product they are actually trying to build.

Lambda MicroVMs is purpose-built for exactly this gap. Each MicroVM gives a single end user or session its own isolated environment that launches rapidly, retains memory and disk state for the length of the session, and pauses to a low idle cost when the user steps away. Because the same Firecracker technology already underpins AWS Lambda Functions, you inherit the operational maturity of a service that has been running this stack at scale.

Let’s try it out
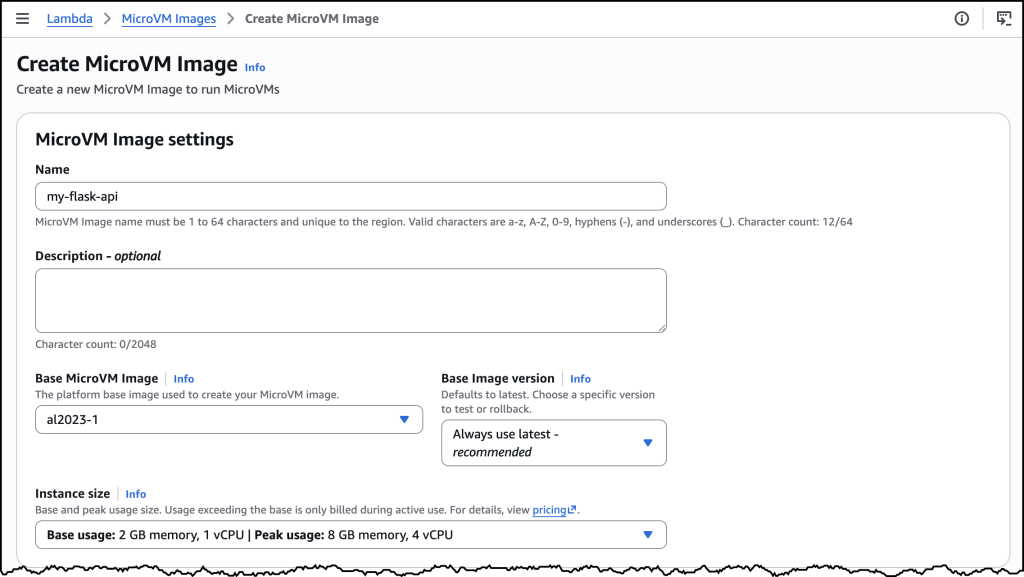
To get started, I navigated to the AWS Lambda console, where Lambda MicroVMs now appears in the left-hand navigation menu. I first need to create a MicroVM Image.

I packaged a Flask web app and its Dockerfile into a zip file, uploaded it to an Amazon Simple Storage Service (Amazon S3) bucket.

My Flask API – app.py

import logging

from flask import Flask, jsonify

app = Flask(__name__)
logging.basicConfig(level=logging.INFO)


@app.route("/")
def hello():
    app.logger.info("Received request to hello world endpoint")
    return jsonify(message="Hello, World!")


if __name__ == "__main__":
    app.run(host="0.0.0.0", port=5000)

My Dockerfile


FROM public.ecr.aws/lambda/microvms:al2023-minimal
RUN dnf install -y python3 python3-pip && dnf clean all

WORKDIR /app

COPY requirements.txt .
RUN pip install --no-cache-dir -r requirements.txt

COPY app.py .

EXPOSE 5000

CMD ["gunicorn", "--bind", "0.0.0.0:5000", "app:app"]

I used the following command to create my MicroVM Image.

aws lambda-microvms create-microvm-image \
--code-artifact uri=<path/to/s3/artifact.zip> --name <VM_image_name> \
--base-image-arn arn:aws:lambda:us-east-1:aws:microvm-image:al2023-1 \
--build-role-arn <IAM role ARN>

You can also create the MicroVM Image in the AWS Console as in the image above. Once I ran the command, Lambda retrieved the zip, ran the Dockerfile, initialized the application, and took a Firecracker snapshot of the running disk and memory state. Build logs streamed in real time to Amazon CloudWatch under /aws/lambda/microvms/<image-name>, and when the image was ready it appeared in the console with its Amazon Resource Name (ARN) and version number.

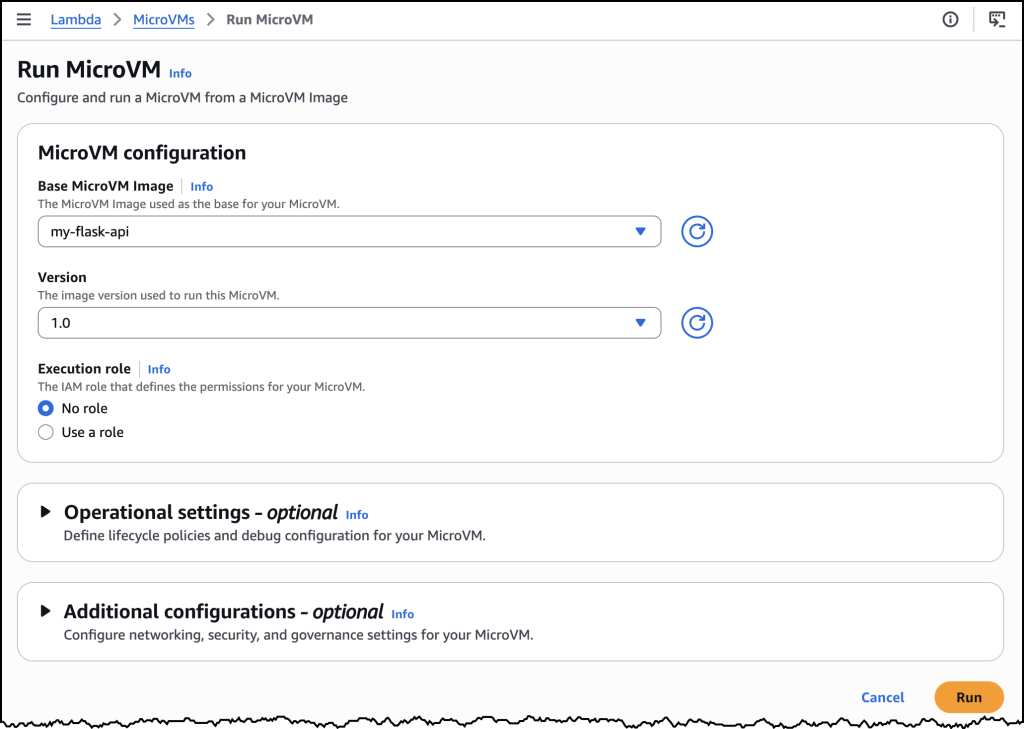
aws lambda-microvms run-microvm \
--image-identifier arn:aws:lambda:<region>:<acct>:microvm-image:my-image \
--execution-role-arn arn:aws:iam::<acct>:role/MicroVMExecutionRole \
--idle-policy '{"maxIdleDurationSeconds":900,"suspendedDurationSeconds":300,"autoResumeEnabled":true}'

Launching can also be done via the AWS Console or the CLI. I passed the image ARN and an idle policy configured to auto-suspend after 15 minutes of inactivity and auto-resume on the next incoming request. No networking setup was required. Lambda assigned the MicroVM a unique ID, returned a dedicated endpoint URL, and started a new MicroVM with my Flask app already running, since it was resumed from a snapshot. My Flask app was already running the moment the launch completed. One API call to get a fully initialized, bootstrapped compute environment.

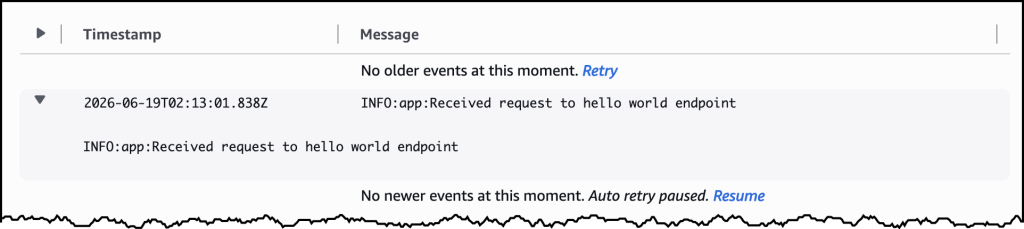
To send traffic, I generated a short-lived auth token with the CLI and attached it to a plain HTTPS request using the X-aws-proxy-auth header. The request landed on my Flask app immediately. I then let the MicroVM sit idle past the suspend threshold, at which point the MicroVM was suspended, with its memory and disk state snapshotted and stored. I then sent another request, and it resumed with the application state fully intact. From the client side, the pause never happened.

How it works
Under the covers, Lambda MicroVMs delivers three capabilities that, until today, no single AWS compute service offered together. The first is virtual machine level isolation, which comes from Firecracker. Each session runs in its own dedicated MicroVM with no shared kernel and no shared resources between users, so untrusted code supplied by one user is contained to their execution environment, without access to other environments or the underlying system. The second is rapid launch and resume. The model is image-then-launch: you create a MicroVM Image by supplying a Dockerfile and code packaged as a zip artifact in Amazon S3, and Lambda runs your Dockerfile, initializes your application, and takes a Firecracker snapshot of the running environment’s memory and disk state. Every subsequent MicroVM launched from that image resumes from the pre-initialized snapshot rather than booting cold, which means launches and idle resumes both achieve near-instant startup latency. Even a multi-gigabyte interactive session comes back online quickly enough to feel responsive to the end user. The third is stateful execution. A running MicroVM retains memory, disk, and running processes across the user’s session. During idle periods, a MicroVM can be suspended – with memory and disk state intact – and resumed when traffic arrives. Installed packages, loaded models, and working filesets are readily available when the user resumes their session. MicroVMs support up to 8 hours of total runtime and can be suspended automatically after a configurable idle window, which makes it straightforward to build products as varied as software vulnerability scans that complete in minutes, data analytics applications that run for hours, and interactive coding sessions with extended idle periods. As Lambda MicroVMs are started from pre-initialized snapshots, applications generating unique content, establishing network connections, or loading ephemeral data during initialization may need to integrate with service-provided hooks for compatibility.

Lambda MicroVMs is a new resource within AWS Lambda, with a distinct API surface. Lambda Functions remain the right choice for event-driven, request-response workloads, and Lambda MicroVMs is purpose-built for multi-tenant applications that need to hand each end user or session their own isolated environment to execute user- or AI-generated code. The two complement each other. An application using Lambda Functions for its event-driven backbone can call into Lambda MicroVMs for the steps that need to run untrusted code in isolation. You bring the application, and the service delivers the execution environment.

Now available
AWS Lambda MicroVMs is available today in the US East (N. Virginia, Ohio), US West (Oregon), Europe (Ireland) and Asia Pacific (Tokyo) Regions, on the ARM64 architecture, with up to 16 vCPUs, 32 GB of memory, and 32 GB of disk per MicroVM. Idle MicroVMs can be suspended explicitly through an API call or automatically through a lifecycle policy, which reduces the running cost while preserving full state for fast resume. Pricing details can be found on the AWS Lambda pricing page.

To get started, visit the AWS Lambda console, or learn more on the Lambda MicroVMs product page. For documentation, see the Lambda MicroVMs Developer Guide.

AWS Weekly Roundup: NY Summit recap, Local Zone in Hanoi, Grok 4.3 in Bedrock, price reductions, and more (June 22, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-ny-summit-recap-local-zone-in-hanoi-grok-4-3-in-bedrock-price-reductions-and-more-june-22-2026/

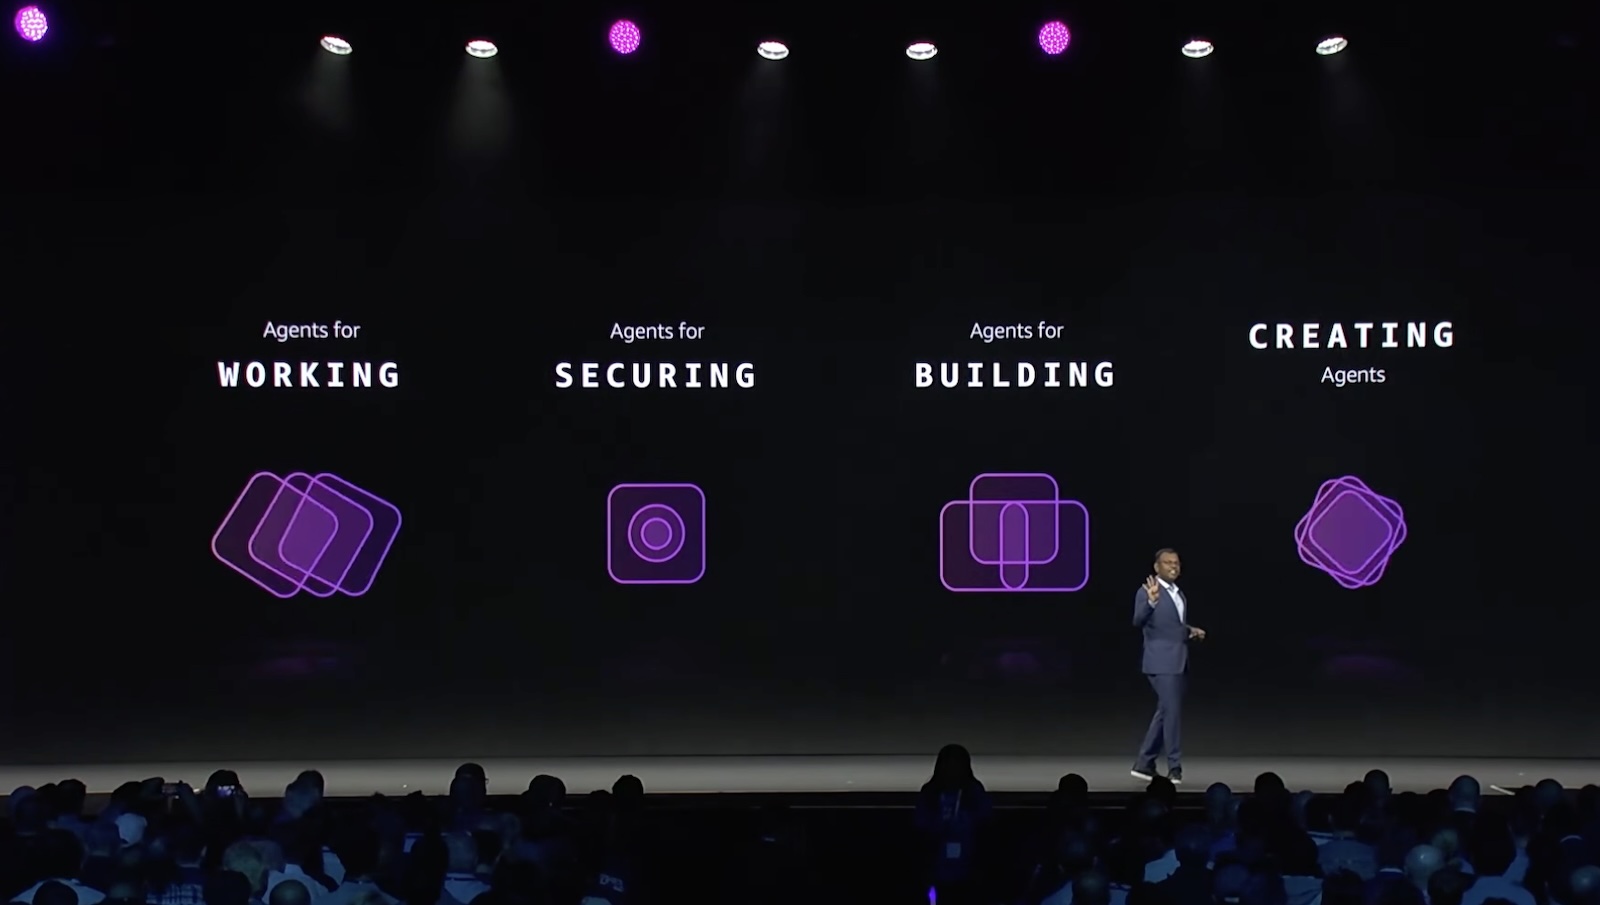
Last week AWS Summit New York City brought together thousands of customers, partners, and builders for a free, one-day event showcasing the latest in cloud and AI innovation. Dr. Swami Sivasubramanian, VP of Agentic AI at AWS unveiled a stack of AI launches in his keynote, all built around one thesis: agents that compound value over time.

  • Agents for working – You can launch autonomous agents and access a smarter activity feed with new Amazon Quick features, which now let you create and run multi-step agents directly in the desktop app and consolidates email, Slack, calendar, and tasks into a single prioritized view with personalized rules.
  • Agents for securing – You can shift from reactive to proactive security with AWS Continuum, a new AI-native security service that reasons, validates, and acts at machine speed across the full code vulnerability lifecycle. AWS Security Agent (now part of AWS Continuum) adds new features: threat modeling; pull request code scanning with remediation across major Git platforms; and IDE integrations via Kiro power, Claude Code plugin, and MCP.
  • Agents for building – You can write, ship, and modernize code in one continuous loop with Kiro, AWS DevOps Agent, and AWS Transform. Kiro introduces a native iOS app; AWS DevOps Agent adds release management capabilities to assess code changes before production; and AWS Transform continuous modernization reduces tech debt autonomously.
  • Agents customers create – You can go from agent idea to production in minutes with Amazon Bedrock AgentCore, which now includes a GA harness for infrastructure and orchestration, Web Search, Managed Knowledge Base, policy integrations with Guardrails, and the new AWS Context service for mapping organizational data relationships.

To learn more, visit the Summit recap from our top announcements blog post and Amazon News post.

Last week’s launches
Here are last week’s launches that caught my attention:

  • AWS Local Zone in Hanoi, Vietnam  —This new Local Zone is one of the first AWS Local Zones in the Asia Pacific with support for Amazon S3 and Amazon EBS Local Snapshots, enabling customers to meet data residency requirements by storing and backing up data locally. To get started, enable the Hanoi Local Zone (ap-southeast-1-han-1a) from the Regions and Zones tab in the AWS Global View or by using the ModifyAvailabilityZoneGroup API.
  • AWS Blocks, an open-source TypeScript framework for application developers (preview) — AWS Blocks runs a fully functional local environment with Postgres, authentication, and real-time messaging, no AWS account required. When you’re ready to deploy, the same application code runs on production AWS services with zero changes, and you can drop into AWS CDK at any point for direct resource configuration.
  • Grok 4.3 from xAI in Amazon Bedrock —You can use the Grok 4.3 model on Amazon Bedrock, giving you even more choice as you build generative AI applications across reasoning, agentic, and enterprise workflows. Grok 4.3 runs on a new inference engine in Bedrock designed for price performance, with support for tool calling, structured output, and response streaming.
  • Amazon S3 annotations: attach rich, queryable context directly to your objects — Amazon S3 now lets you attach up to 1 GB of rich, mutable, and queryable context directly to your objects using annotations, purpose-built for AI agents and autonomous workflows that need to discover, understand, and act on data at scale without maintaining separate metadata systems.
  • Amazon ECS announces faster service auto scaling — Amazon ECS service auto scaling now detects and responds to load changes faster with support for high resolution (20-second) metrics and metric publishing optimizations. In AWS benchmarking tests, time to trigger scale-out improved from 363 seconds to 86 seconds (76% faster), and total time to scale and provision new tasks improved from 386 seconds to 109 seconds (72% faster).
  • Amazon EC2 G7 instances accelerated by NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs — AWS is the first major cloud provider to support NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs. G7 instances are accelerated by these GPUs with custom sixth-generation Intel Xeon Scalable processors, delivering up to 4.6x AI inference performance and up to 2.1x graphics performance compared to G6 instances.
  • Strands Agents introduces new capabilities — Strands is an open source toolkit for building production agents. You can now use better context management in Harness SDK, a new isolated execution environment with Strands Shell, and chaos testing and red teaming in Strands Evals.
  • AWS Management Console Private Access – You can access the AWS Console from VPCs without internet connectivity, allowing enterprises to manage their AWS infrastructure through the console while maintaining strict network security controls in air-gapped environments.
  • AWS Marketplace Storefront is now generally available – AWS Partners can create and deploy their own branded catalog of solutions and services on their website or application in hours. Channel Partners and Independent Software Vendors can now simplify how they manage their cloud marketplace business and make it easier for customers to discover and purchase their solutions from AWS Marketplace.
  • Palo Alto Networks (PANW) Advanced DNS Security on Amazon Route 53 Resolver DNS Firewall (preview) – You can now enforce DNS threat protections from Palo Alto Networks directly on Route 53 DNS Firewall rules, without deploying separate firewalls or modifying VPC configurations — by subscribing to PANW from the DNS Firewall console through the embedded AWS Marketplace widget.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Price reductions 
AWS continues to look for ways to increase performance and lower prices for our customers. I noticed a few such efforts last week, so I’d like to share them:

Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

Announcing Amazon EC2 G7 instances accelerated by NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/announcing-amazon-ec2-g7-instances-accelerated-by-nvidia-rtx-pro-4500-blackwell-server-edition-gpus/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) G7 instances, delivering high performance GPU acceleration for AI inference, graphics, and data analytics workloads.

AWS is the first major cloud provider to support NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs. G7 instances are accelerated by these GPUs with custom sixth-generation Intel Xeon Scalable processors, delivering up to 4.6x AI inference performance and up to 2.1x graphics performance compared to G6 instances. G7 instances also deliver faster performance for GPU-accelerated analytics on Amazon EMR on Amazon Elastic Kubernetes Service (Amazon EKS). G7 instances are well suited for a broad range of GPU-enabled workloads including AI inference, graphics rendering, video transcoding and analytics, spatial computing, virtual desktop infrastructure (VDI), and data analytics.

Here are improvements of G7 instances compared to previous generation:

  • Faster GPU memory – NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs offer 1.33 times the GPU memory capacity and 2.45 times the GPU memory bandwidth compared to G6 instances. With 32 GB of GPU memory per GPU, 5th Gen Tensor Cores, and 4th Gen RT Cores, G7 instances deliver enhanced AI inference and graphics performance.
  • High performance networking and storage – G7 instances come with 700 Gbps of EFA-enabled networking throughput (7x compared to G6) enabling the low-latency, high-bandwidth connectivity that AI inference, graphics-intensive applications, and GPU-accelerated data analytics workloads need to perform at their best. G7 instances support up to 7.6 TB local NVMe SSD storage, enabling you to keep large models and datasets close to compute, reduce data transfer overhead, and improve throughput.
  • Advanced video encoding and decoding engines – Ninth-generation NVENC and sixth-generation NVDEC engines support 4:2:2 encoding and decoding for high-resolution video workflows, delivering 1.5x concurrent video streams compared to previous-generation G6 instances.

EC2 G7 instance specifications
G7 instances feature up to 8 NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs with up to 256 GB of total GPU memory (32 GB of memory per GPU) and custom Intel Xeon Scalable processors. They also are available in 7 sizes and support up to 192 vCPUs, up to 700 Gbps of network bandwidth, up to 768 GiB of system memory, and up to 7.6 TB of local NVMe SSD storage.

Here are the specs:

Instance name GPUs GPU memory (GB) vCPUs Memory (GiB) Storage EBS bandwidth (Gbps) Network bandwidth (Gbps)
g7.2xlarge 1 32 8 32 1 x 600 Up to 8 Up to 60
g7.4xlarge 1 32 16 64 1 x 600 8 Up to 100
g7.8xlarge 1 32 32 128 1 x 950 16 Up to 100
g7.12xlarge 2 64 48 192 1 x 1900 20 175
g7.24xlarge 4 128 96 384 1 x 3800 40 350
g7.48xlarge 8 256 192 768 2 x 3800 80 700
g7.metal* 8 256 192 768 2 x 3800 80 700

* Coming soon

G7 instances support NVIDIA GPUDirect P2P for multi-GPU sizes, NVIDIA GPUDirect RDMA with EFA, and GPUDirect RDMA with EFA for Amazon FSx for Lustre, enabling low-latency GPU-to-GPU communication for multi-GPU and multi-node workloads.

To get started with G7 instances, you can use the AWS Deep Learning AMIs (DLAMI) or NVIDIA Workstation AMIs with prepackaged GPU drivers for your AI inference and graphics workloads. To use G7 instances with Amazon EKS, build EKS AMIs with NVIDIA driver version R595 with EKS-provided automation. G7 instances support multiple operating systems including Amazon Linux, Ubuntu, RHEL, and Windows Server, with comprehensive NVIDIA driver integration providing compatibility with industry-standard graphics libraries including DirectX, Vulkan, and OpenGL.

Get started today
You can start using Amazon EC2 G7 instances today in two AWS regions: US East (Ohio) and US West (Oregon). To check future Regional expansion plans, look up the instance type in the CloudFormation resources tab on the AWS Capabilities by Region page.

G7 instances are offered through multiple purchasing options, including On-Demand, Savings Plans, and Spot Instances. Dedicated Instances are also supported for the 12xlarge, 24xlarge, and 48xlarge sizes. For detailed pricing, visit the Amazon EC2 Pricing page.

Ready to get started? Launch G7 instances from the Amazon EC2 console. For more details, head over to the Amazon EC2 G7 instances page. We’d love to hear your feedback. Share it on AWS re:Post for EC2 or reach out through your usual AWS Support contacts.
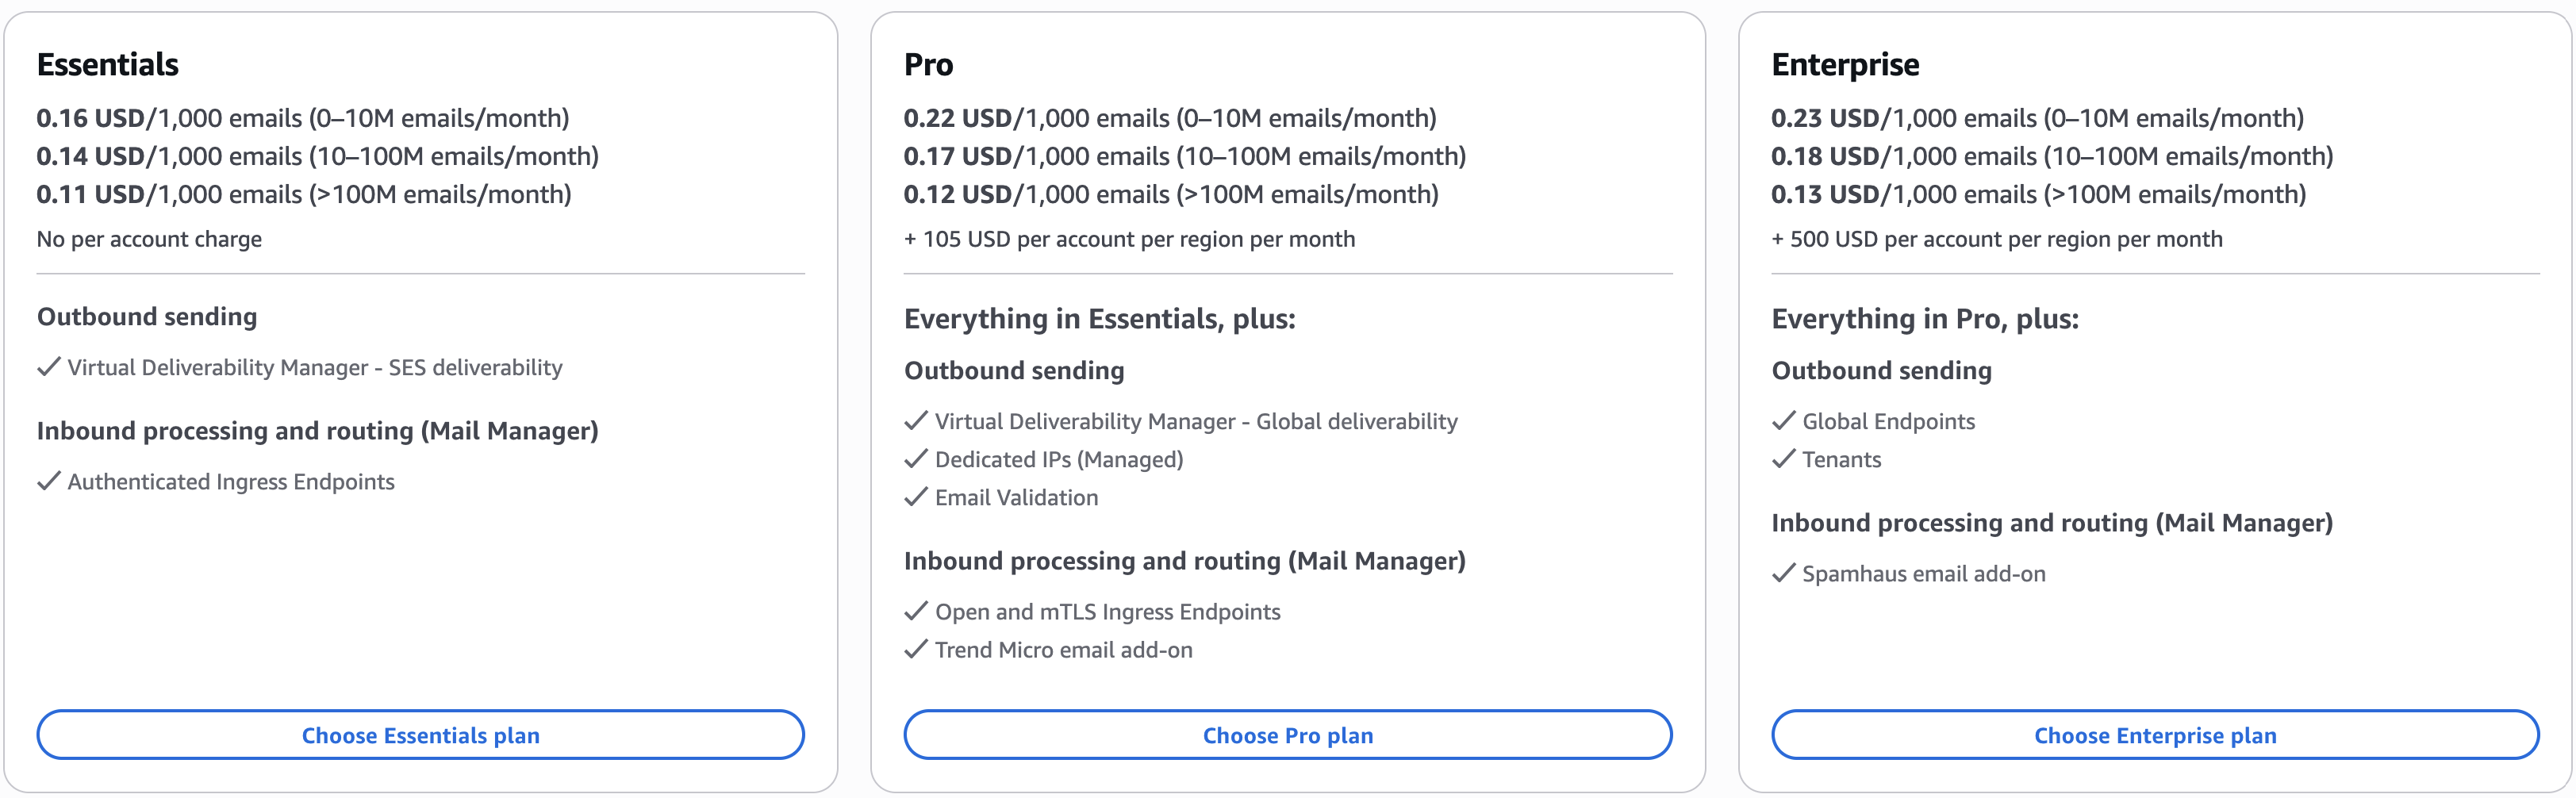
– Daniel Abib

Amazon ECS introduces new high-resolution metrics for faster service auto scaling

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-ecs-introduces-new-high-resolution-metrics-for-faster-service-auto-scaling/

Amazon Elastic Container Service (Amazon ECS) service auto scaling automatically adjusts task counts to meet workload demand with comprehensive scaling policies, including predictive scaling for recurring traffic patterns, scheduled scaling for planned events, and target tracking to scale dynamically on real-time metrics.

You can choose proactive scaling by using predictive scaling (automatic) and scheduled scaling (customer-defined), or reactive scaling by using target tracking with just a target to scale on. Amazon ECS service auto scaling adjusts the number of tasks in an ECS service based on Amazon CloudWatch metrics, such as average CPU/Memory usage, request count per target, a custom metric such as queue depth, or demand surges by using advanced machine learning (ML) algorithms.

With today’s launch, Amazon ECS service auto scaling now detects and responds to load changes faster with support for high resolution (20-second) metrics and metric publishing optimizations. In AWS benchmarking tests, time to trigger scale-out improved from 363 seconds to 86 seconds (76% faster, 4.2x), and total time to scale and provision new tasks improved from 386 seconds to 109 seconds (72% faster, 3.5x)

This launch delivers three key benefits for your applications:

  • Improved performance and reliability: Faster scaling means, your application responds faster to demand surges, reducing latencies or failures for end users during demand surges.
  • Right-size without compromise: Depending on the workload, you can reduce baseline task counts because scale-out now happens fast enough to handle traffic spikes without preemptive capacity padding. This directly reduces compute costs while maintaining application performance and availability.
  • Simpler scaling configuration: Target tracking with high-resolution metrics delivers the aggressive scaling behavior that previously required custom scaling configurations, such as usage of step-scaling policies. One configuration change replaces custom engineering work.

How it works
To use ECS faster service auto scaling, first enable high-resolution metrics for your ECS service, and then configure a target tracking scaling policy which uses high-resolution metrics. ECS faster service autoscaling works across all compute options on ECS: AWS Fargate, ECS Managed Instances, and Amazon Elastic Compute Cloud (Amazon EC2). You can enable these metrics when you create or update your ECS service in the Amazon ECS console, or using AWS SDKs and tools, and AWS CloudFormation.

When you create a service in the console, add 20-seconds resolution metrics in the Monitoring configuration section. These metrics incur additional CloudWatch costs while the standard resolution (60-seconds) is free.

In the Service auto scaling section, check Use service auto scaling and choose Target Tracking for the scaling policy type to use real-time data to scale the number of tasks that your service runs based on demand.

Then, choose a Scaling policy type for the target tracking. You can select ECSServiceAverageCPUUtilizationHighResolution or ECSServiceAverageMemoryUtilizationHighResolution as new metrics.

That’s it – your ECS service will use high resolution metrics for auto scaling.

To update an existing ECS service to use faster auto scaling, you first need to configure high resolution metrics via Update Service. Once deployment completes, your service will generate high-resolution metrics. You can then go to the Service and auto scaling tab from your service details to update scaling policy to use higher resolution metrics.

That’s all you need. Your ECS service now evaluates scaling decisions at 20-second intervals.

You can also use the AWS Command Line Interface (AWS CLI) to enable new metrics in your ECS service through Application Auto Scaling. To learn more, visit the faster auto scaling documentation.

Now available
Faster service autoscaling with high-resolution metrics for Amazon ECS is available today. The feature itself has no additional cost, but high-resolution CloudWatch metrics introduce a new pricing dimension. For details, see the CloudWatch pricing page.

Give it a try today and send feedback to AWS re:Post for ECS or through your usual AWS Support contacts.
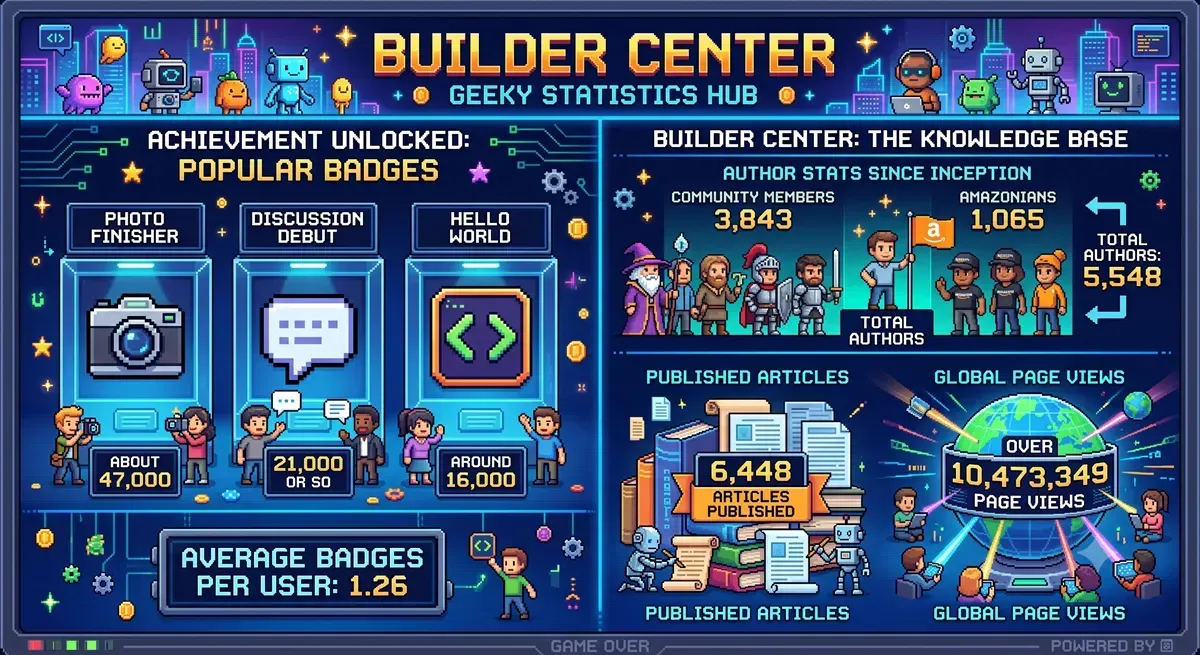
— Channy

Introducing Amazon Bedrock Managed Knowledge Base for faster, more accurate enterprise AI applications

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/introducing-amazon-bedrock-managed-knowledge-base-for-faster-more-accurate-enterprise-ai-applications/

Today, we’re announcing Amazon Bedrock Managed Knowledge Base, a new set of capabilities that enables developers to build enterprise-grade generative AI applications with their proprietary data in minutes. Organizations building agentic AI applications need secure, reliable, and up-to-date access to enterprise-wide data to deliver accurate, fast, and trusted outcomes. Managed Knowledge Base abstracts away the complexity of building and managing retrieval-augmented generation (RAG) pipelines, allowing developers to focus on business outcomes rather than infrastructure management.

Developers building knowledge bases for their agents face three key challenges today:

  • Connecting to enterprise data – Enterprise knowledge lives across disparate systems with different content types, access control lists, and document formats. Building and maintaining custom connectors for each source adds complexity that slows down development.
  • Optimizing RAG accuracy – Best practices for retrieval-augmented generation keep evolving. Developers need to experiment with different parsing strategies, chunking approaches, embedding models, and agentic retrieval behaviors to get accurate answers from their data.
  • Managing infrastructure at scale – Organizations need to serve large knowledge bases with millions of documents, or manage thousands of smaller knowledge bases across teams. Both patterns require reliable infrastructure, security enforcement, and cost control.

These challenges require developers to repeatedly perform undifferentiated work instead of focusing on their applications.

Amazon Bedrock Managed Knowledge Base addresses these challenges by abstracting away the multiple infrastructure components developers traditionally have to assemble and maintain themselves (storage, retrieval, embeddings, re-ranking, and foundation model selection) into a single managed primitive. By default, the service automatically selects and manages a default embeddings model, re-ranker model, and foundational model on your behalf, so you can get up to speed quickly without needing to pick or maintain one yourself. On top of this managed foundation, three core innovations further improve ease of use and accuracy:

  • Native data connectors – Six pre-built ingestion connectors that natively pull enterprise data and permissions from SaaS applications, eliminating the overhead developers face in managing application-specific requirements. At launch, we support Amazon S3, SharePoint, Confluence, Web Crawler, Google Drive, and OneDrive.
  • Smart Parsing – Different content types and sources require different approaches to achieve accurate retrieval. Smart Parsing handles this complexity automatically, selecting the right parsing strategy for each data type and connector to provide the highest accuracy for your agents.
  • Agentic Retriever – Optimized for complex queries that require multiturn, multihop retrieval within a single knowledge base or across multiple knowledge bases. Agentic Retriever automatically infers end-user intent and draws relevant context from institutional knowledge spread across data sources and modalities.

With just a few lines of code, Amazon Bedrock Managed Knowledge Base automatically manages and scales the end-to-end RAG pipeline that powers your enterprise knowledge agents. For agent builders, it’s available as a pre-built target type in Amazon Bedrock AgentCore Gateway, reducing integration to a few lines of code, auto-generating role-based permissions, and providing observability and evaluation metrics in the AgentCore Observability dashboard.

Getting started with Amazon Bedrock Managed Knowledge Base
Creating a Managed Knowledge Base is straightforward. Navigate to the Amazon Bedrock AgentCore console or the Amazon Bedrock console, open the Knowledge Bases page, and choose Create Managed KB. The experience is the same in both consoles. You will see that Unstructured Vector Store KB is now available as the recommended option, alongside the other knowledge base types you may already be familiar with:

Picture 1 – Knowledge Bases list page in the Amazon Bedrock AgentCore console showing the Type column with different KB types and the Create Managed KB button

When creating a new Knowledge Bases, you can connect to your enterprise data sources by choosing from the list of supported connectors directly from a dropdown. AWS Identity and Access Management (IAM) roles are automatically created, and you can choose to edit these permissions if needed:

Picture 2 – Create Knowledge Base page showing the Data source dropdown expanded with all supported connectors: Amazon S3, Confluence, Custom, Google Drive, One Drive, SharePoint, and Web Crawler

An optimized set of defaults will be presented, allowing you to create your knowledge base in just a few clicks. Once the data is synced, you can integrate the knowledge base with your agent or provide it as a tool for your foundation model and start querying.

Smart Parsing for accurate data ingestion
One of the key challenges in building knowledge bases is preparing diverse data types for accurate retrieval. Once you point Managed Knowledge Base at your data sources, Smart Parsing automatically determines the optimal parsing strategy for each data type and connector, no extra configuration is required.

Smart Parsing combines multiple techniques:

  • Connector-specific data models – Optimized handling for each data source. For example, the Web Crawler connector preserves HTML structure including embedded images and tables, ensuring rich content is not dropped during ingestion. SharePoint connectors maintain document hierarchy and relationships between files.
  • Multimodal processing – Automatic detection and processing of different content types within documents. The system identifies bounding boxes in documents, then sends them to foundation models for data extraction, captioning, and scene description in video files.
  • Optimized chunking – Smart Parsing leverages foundation models to understand document structure and extract meaningful content, ensuring that complex documents with mixed formats are properly indexed. Intelligent defaults balance retrieval accuracy with performance based on document type and content structure, while advanced users can customize chunking strategies when needed.

This automated approach eliminates weeks of experimentation typically required to achieve production-quality retrieval accuracy, while still preserving the flexibility to customize when needed.

Using Agentic Retriever for complex queries
After your data is ingested, you can start querying your knowledge base. Generative AI applications often struggle with complex user queries that require reasoning, recursive multi-step retrieval, and intermediate evaluations of results. Consider a user asking two related questions: “What is the cloud infrastructure budget for the ML platform team?” and “Does our expense policy allow prepaying annual commitments?” A single retrieval step might surface documents about the ML platform team but fail to connect the budget information with the expense policy needed to fully answer the question.

Picture 3 – Agentic Retriever decomposes complex user queries into a step-by-step plan, performing multi-hop retrieval across multiple knowledge bases and combining results to deliver accurate, grounded responses

Agentic Retriever solves this by creating a step-by-step query plan: 1. Which team owns the ML platform, and what is their cloud infrastructure budget? 2. What does the expense policy say about prepaying annual commitments? 3. Does the policy allow the ML platform team to prepay against this budget?

The system performs multi-hop retrieval and reasoning at each step, and once it has gathered sufficient relevant passages, it stops the search process and returns the top results. By abstracting away the complexity of building a separate multi-hop reasoning pipeline, this approach dramatically improves accuracy for complex queries while letting developers focus on their agentic search applications instead of orchestration logic.

You can try Agentic Retriever directly from the test panel of your knowledge base in the Amazon Bedrock AgentCore console. Select Agentic retrieval only as the retrieval type to let the system automatically plan and execute multi-step queries across your knowledge bases:

Picture 4 – Test Knowledge Base panel showing Agentic retrieval with answer generation selected as the retrieval type, with model selection and maximum agentic iterations options

Enabling MCP with Bedrock AgentCore
Amazon Bedrock Managed Knowledge Base seamlessly integrates with AgentCore Gateway as a native target type. This integration eliminates the need for manual integration and provides built-in observability, policy enforcement, and automatic permission management.

You can navigate to the Amazon Bedrock AgentCore console or SDK and create an AgentCore Gateway or select an existing one. When adding targets to your gateway, you will find Knowledge Base as a new pre-built target type alongside other options such as MCP server, Lambda ARN, REST API, and other integrations. Simply select your knowledge base ID to expose it through the gateway:

Picture 5 – Add targets page in AgentCore Gateway showing Knowledge Base as a new pre-built target type, with the knowledge base ID selector and runtime retrieval mode options

Add targets page in AgentCore Gateway showing Knowledge Base as a new pre-built target type, with the knowledge base ID selector and runtime retrieval mode options

Gateway exposes the standard Model Context Protocol (MCP), so the knowledge base tools are automatically discovered by clients from any MCP-compatible framework, including Strands Agents, LangChain, CrewAI, LlamaIndex, and LangGraph. No custom integration code is required.

Model choice and flexibility
Amazon Bedrock Managed Knowledge Base preserves the flexibility developers expect from Amazon Bedrock. Every foundation model available on Bedrock can power the generation step, and developers can select from different embedding and re-ranking models to optimize retrieval for their specific use case, enabling teams to fine-tune accuracy and cost-performance without changing infrastructure.

Unlike managed solutions that lock you into specific model providers, Amazon Bedrock Managed Knowledge Base separates the infrastructure management (connectors, parsing, storage, retrieval orchestration) from model selection. This means you can:

  • Take advantage of the latest models – Adopt the latest embedding, re-ranking, and foundation models as they become available to improve accuracy, latency, and cost for your application without rebuilding your RAG pipeline.
  • Optimize for price-performance – Choose smaller, faster models for simple queries and more capable models for complex reasoning tasks, all using the same knowledge base infrastructure.
  • Use Bedrock embedding models – While Smart Parsing provides optimized defaults, you can configure Bedrock embedding models when your domain requires specialized semantic understanding.
  • Maintain consistency with existing applications – If you’re already using Bedrock Knowledge Bases APIs (Retrieve, StartIngest, StopIngest, IngestKnowledgeBaseDocuments), Managed Knowledge Base uses the same APIs, so migration requires no code changes, just point to the new knowledge base ID.

This approach ensures you can spend time on your generative AI application without losing the ability to change models based on evolving requirements or new model capabilities.

Get started today
Amazon Bedrock Managed Knowledge Base is available today in the US East (N. Virginia), US West (Oregon), Asia Pacific (Sydney, Tokyo), Europe (Dublin, Frankfurt, London), and AWS GovCloud (US-West) Regions. For Regional availability and future roadmap, visit AWS Capabilities by Region.

With Bedrock Managed Knowledge Base, you pay for what you use with no upfront commitments. Pricing is based on two dimensions: the size of indexed data stored and the number of retrievals performed (on-demand). For detailed pricing information, visit the Amazon Bedrock pricing page. Bedrock is also a part of the AWS Free Tier that new AWS customers can use to get started at no cost and explore key AWS services.

These capabilities work with any open source framework such as CrewAI, LangGraph, LlamaIndex, and Strands Agents, and with any foundation model. Bedrock services can be used together or independently, and you can get started using your favorite AI-assisted development environment with the AgentCore open source MCP server.

To learn more and get started quickly, visit the Bedrock Knowledge Bases Developer Guide.

Daniel Abib

Announcing Web Search on Amazon Bedrock AgentCore: Ground your AI agents in current, accurate web knowledge

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/announcing-web-search-on-amazon-bedrock-agentcore-ground-your-ai-agents-in-current-accurate-web-knowledge/

Today, we’re announcing the general availability of Web Search on Amazon Bedrock AgentCore, a fully managed tool that enables agents to ground responses in current, cited web knowledge with zero data egress from customer’s secured AWS environment.

Web Search uses a built-in connector target on Bedrock AgentCore Gateway using the Model Context Protocol (MCP). Your agent sends a natural-language query, and Web Search returns most relevant snippets, source URLs, titles, and publication dates that the model can reason over to produce a grounded response.

It is built on Amazon’s search infrastructure, informed by years of experience powering agentic search experiences across Alexa+, Amazon Quick, and Kiro. It uses a multi-source grounding approach that combines Amazon’s web index with structured knowledge graph data. Beyond standard web results, this gives agents access to Amazon Knowledge Graph with verified facts, helping them retrieve more relevant and accurate responses than traditional web search alone.

With this launch, you can focus on building agents instead of manually adding web search to agents on Bedrock AgentCore and managing its infrastructure. Your AI agent looks at user question, retrieves the latest facts, and then takes any necessary action grounded in current developments beyond a model’s training data. You can also meet enterprise governance policies without sending user prompts and retrieval queries to external search API providers outside of AWS.

Web Search on Bedrock AgentCore in action
To get started, create the Bedrock AgentCore Gateway with Web Search tool target in the Bedrock AgentCore console. When the Gateway URL is created, you can interact with API call, Command Line Interface (CLI), or MCP Inspector.

To add Web Search tool target when creating the Gateway, choose MCP target as a target protocol and Connectors as a target type. You can select the Web Search tool as a preconfigured target to retrieve most relevant web search results including links, snippets, and metadata.

After creating your gateway, you can find the Web Search tool target on the detail page of your gateway. You can also add a new Web Search tool target to an existing gateway.

To interact with Web Search tool, use the sample invocation code in the View invocation code section. You can use code snippets through Python codes with API requests, MCP Python SDK, Strands MCP Client, and MCP Inspector.

For example, you can interact with the MCP Inspector, an interactive developer tool for testing and debugging MCP servers. When you connect to the MCP server through the Gateway resource URL, you will find a Web Search tool for each connector target on the Gateway. Enter input the web search query and choose Run Tool to get the results.

To learn more about how to use Web Search on Bedrock AgentCore, visit the Bedrock AgentCore Gateway documentation.

Customer voices
Some of our customers had early access to this new feature. This is what they shared with us:

Benchling helps scientists accelerate R&D, making it easy to centralize scientific data, collaborate across teams, and access insights. Nicholas Larus-Stone, Head of AI Agents at Benchling shared “Scientists using Benchling AI can now ask about a target they’re actively working on and get answers grounded in both their institutional data in Benchling and published literature. The result is more complete science, and hypothesis generation done right. Because we’re using the Web Search tool on Amazon Bedrock AgentCore, customers have a secure, governed environment to bring that high quality published data into their workflows without compromising how they manage their data.”

Gen Digital leads consumer and small business cyber safety, offering antivirus, antimalware, identity and privacy protection, virtual private networks, and cloud backup. Iskander Sanchez-Rola, Senior Director of AI & Innovation, Gen Digital shared “With the Web Search tool on Amazon Bedrock AgentCore, Norton Revamp helps professionals build their online reputation with current, grounded content ideas shaped by what’s actually happening in the world today. What we value most is that AWS uses its own search index and keep queries within our trusted AWS environment.”

To read more customer stories, visit the Amazon Bedrock Customers.

Now available
Web Search on Amazon Bedrock AgentCore is generally available today in the US East (N. Virginia) Region. For Regional availability and a future roadmap, visit the AWS Capabilities by Region.

You can get started with Web Search on Bedrock AgentCore at no additional cost. You pay only for the data transfer charges you use for the Gateway. New AWS customers also receive up to $200 in Free Tier credits. To learn more, visit the Amazon Bedrock AgentCore pricing page.

Try it in the Amazon Bedrock AgentCore console and send feedback to AWS re:Post for Amazon Bedrock AgentCore or through your usual AWS Support contacts.
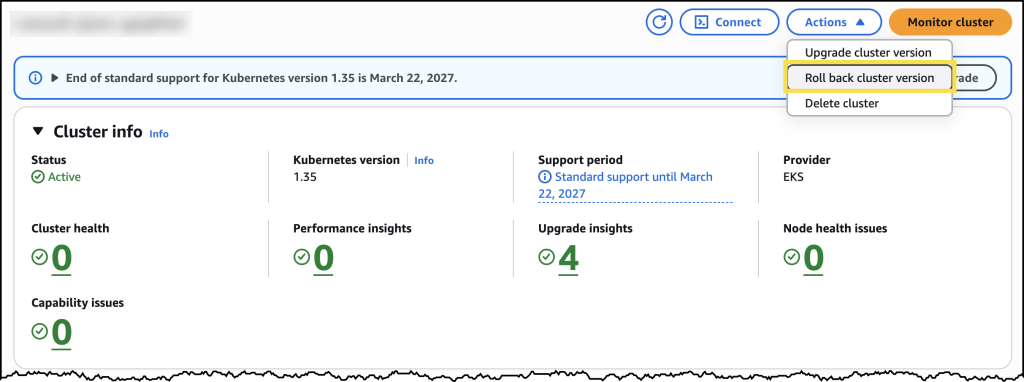
— Channy

Proactively reduce tech debt autonomously with AWS Transform – continuous modernization (preview)

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/proactively-reduce-tech-debt-autonomously-with-aws-transform-continuous-modernization-preview/

Today, we’re announcing AWS Transform – continuous modernization (preview), a new capability of AWS Transform for continuous, autonomous tech debt analysis and remediation at scale. AWS Transform already helps enterprises migrate out of data centers, modernize mainframe and Windows applications, and handle the undifferentiated work of software maintenance: upgrading Java versions, swapping deprecated frameworks, and updating AWS Lambda runtimes before they reach end of life. This new experience builds on this. Customers get full visibility into the state of their codebase across thousands of repositories, prioritized findings, and the pull requests that make the fixes.

Engineering organizations typically consume up to 30% of IT budgets. Customers stitch together point tools: one to detect dependency issues, another to flag vulnerabilities, another for code quality. But no existing tool detects, prioritizes, and remediates tech debt continuously and at scale. The result is a manual, app-by-app cycle that drains engineering capacity. Leaders fall back on self-reported team status that lags reality and hides regressions. AI-assisted development makes this worse: as coding agents accelerate the pace of change, tech debt accumulates faster than developers can keep up. Customers need a capability that detects, prioritizes, and remediates tech debt continuously, autonomously, and at scale.

Continuous analysis
To address the visibility challenge, this new capability within AWS Transform automatically scans your code repositories against configurable baselines and generates findings in hours, not weeks. Out of the box, AWS Transform – continuous modernization includes policies for detecting end of life dependencies, deprecated frameworks, and other common sources of technical debt. You can also extend these with your own remediation patterns specific to your organization, including approved libraries, internal coding standards, or tech debt policies your platform team already enforces. For example, if your team has deprecated an internal library or prefers a particular logging pattern, you can codify that as a policy and run it across all your repositories continuously.

Unlike periodic manual efforts, continuous analysis provides ground truth directly from your code. When a repository falls behind your baseline, you know immediately, showing which components are behind and by how much, regardless of how the team chooses to address it. This eliminates the need for status check-ins and manual compliance tracking, giving platform teams an always current view of their technical debt landscape.

Autonomous remediation at scale
Once you’ve identified and prioritized findings, you can configure autonomous remediations that generate pull requests for affected repositories automatically. This new AWS Transform capability provides out-of-the-box remediation transformations for common scenarios such as Java version upgrades, SDK migrations, and library updates. You can also create custom transformations for organization-specific patterns.

When you launch a remediation, the continuous modernization capability creates pull requests for each affected repository, notifying the owning team with a message like: “This repository is behind on your organization’s baseline for this dependency. Here’s a PR that resolves it.” Teams can review and merge the PR, or choose to remediate using their own approach. Either way, continuous analysis detects when the fix is in place, providing ground truth without requiring manual confirmation.

AWS Transform – continuous modernization integrates with AWS Security Agent to detect and remediate security vulnerabilities at the source-code level, so security findings flow into the same prioritized list and pull-request workflow as other tech debt.

Let’s try it out
To get started with, I navigated to the AWS Transform web application. From the dashboard, I can see an overview of my organization’s repositories and their current status against my configured baselines.

First, I connected my source control system and initiated an analysis against my specified policies. Within hours, the analysis returned findings across my repositories, showing which ones were behind the baseline and by how much. I could see the severity, the number of affected files, and the specific tech debt patterns detected.

From here, I selected a group of high-priority findings and launched a remediation campaign. AWS Transform – continuous modernization generated pull requests for each affected repository. I could monitor the campaign’s progress in real time, seeing which PRs were created, which were merged, and which repositories returned to compliance.

Image 1: AWS Transform – continuous modernization dashboard showing a portfolio overview of your technical debt findings across all connected repositories.

Image 2: The detailed findings view listing individual tech debt items by severity, category, and repository with their available remediation options.

Image 3: The sources view showing connected repositories from GitHub and local environments that continuous modernization is tracking for analysis.

Faster ways to modernize
These capabilities support two distinct approaches to code modernization. In continuous mode, you can use continuous modernization to keep your codebases current as baselines evolve. Think of this as the day-to-day work of upgrading libraries, applying security patches, and enforcing coding standards across your organization.

For larger modernization projects, such as migrating from one framework to another or upgrading a major runtime version across hundreds of applications, you can use campaign mode for targeted, project-based modernization. AWS Transform custom continues to provide the flexible primitive for these larger efforts. AWS Transform – continuous modernization is purpose-built for the recurring, high-volume work that platform teams manage every day.

Now available
AWS Transform – continuous modernization (preview) is available today. You can get started through the AWS Transform web application, via the AWS Transform Kiro Power, or through MCP and skills for integration with your existing coding agents. To learn more, visit the AWS Transform documentation.

AWS DevOps Agent adds release management capabilities to assess code changes before production (preview)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-devops-agent-adds-release-management-capabilities-to-assess-code-changes-before-production-preview/

Today, we’re announcing a new release management capability in AWS DevOps Agent that is now available in preview. AWS DevOps Agent is your always-available teammate that spans software changes and operations across AWS, multicloud, and on-premises environments. The practice of DevOps aims to make software change and operations smooth and increasingly autonomous, and AWS DevOps Agent delivers on both by leveraging its deep understanding of your environment, your services, their dependencies, and how they behave in production. Already generally available for post-deployment operations, it autonomously investigates incidents, provides root cause analysis and mitigation steps, and delivers targeted recommendations to prevent recurring issues. With today’s preview, AWS DevOps Agent adds release readiness review of code changes and autonomous release testing. These new features verify every change against the natural language standards you give to the DevOps Agent and run change-specific tests in production-like environments. AWS DevOps Agent now supports teams from code creation to production, helping reviewers and testers keep pace with the volume of AI-generated code.

As development teams adopt AI coding tools, the volume of pull requests moving through delivery pipelines has increased faster than review and testing processes can handle. When teams are under pressure to keep up, reviews are approved without thorough examination, and test environments drift from production. The value that coding agents generate sits waiting in review queues instead of reaching end users. At the same time, AI models are increasingly capable of catching functional and security issues that human reviewers might miss under time pressure, making speedy and safe delivery a requirement rather than a tradeoff.

The release readiness review feature evaluates every code change against production requirements, dependency safety, and the standards and best practices you provide to the DevOps Agent. The agent checks cross-repository dependency risks that could affect other services, access control changes against AWS Well-Architected Framework best practices, and compliance with any standards you have defined. When no standards are provided, the agent applies general best practices. As part of the review, the agent also runs your software in an AWS-managed isolated environment, executing lightweight user journey tests to verify the software builds, runs, and passes basic functional checks before the change enters the pipeline. Findings appear in the AWS DevOps Agent console and as comments on pull requests in GitHub or GitLab. You can also invoke reviews directly from your IDE through the Kiro power or Claude Code plugin, so developers can identify and fix dependency risks, standards violations, and access control issues before the change is committed to version control.

The autonomous release testing feature goes further, generating and running change-specific test plans for web and API-based applications in customer-provisioned, production-like environments before the change merges. Rather than running a static test suite, the agent reasons about what the change does and constructs tests tailored to it, covering functional correctness, behavioral regressions, and integration scenarios that a manually maintained test plan might not anticipate. Every test run produces structured artifacts including metrics, logs, traces, and an execution summary, giving reviewers a consistent record of what was tested and what the results were.

Getting started with AWS DevOps Agent release management
This walkthrough shows how to run an on-demand release readiness review using the AWS DevOps Agent web app. Before you begin, confirm that you have at least one GitHub or GitLab repository connected to your Agent Space. Once your repositories are connected, AWS DevOps Agent will index your code and build a knowledge graph of cross-repository and cloud dependencies.

To open the web app, navigate to the AWS DevOps Agent console, select your Agent Space, and choose the Web app tab. Choose Operator access to open the web app.

Without standards configured, the agent applies general best practices. To tailor reviews to your internal standards, navigate to Knowledge, then choose the Instructions tab. You will see a list of instruction sets, each scoped to a specific agent or task. Choose View next to Release readiness review to edit the instructions for production-readiness change review. Write your internal standards in plain English. For example, you can define infrastructure and data standards on encryption or network access rules, best practices that warn without blocking such as logging and observability requirements, and sensitive data classification best practices that identify applications or resources requiring higher security measures. To apply instructions across all agents in your space, choose View next to All agents.

You can trigger a release readiness review in two ways: by submitting a pull request to a connected repository, or by entering an on-demand query in the chat interface. To run an on-demand review from chat, choose New chat and enter a request such as:

Perform a production risk analysis on my repository branch

The agent will ask for the repository and branch you want to analyze. You can provide a branch name, a pull request number, or a commit SHA. Once you confirm your selection, the agent queues the review and analyzes the change for production risks, including infrastructure impacts, configuration changes, and potential issues.

After the review completes, you can ask follow-up questions directly in the chat to explore the findings in more detail. For example, you can ask which downstream consumers a change affects, and the agent will return a structured breakdown of in-repository and cross-repository consumers that will break, the specific files and line numbers affected, and the recommended steps to resolve the issue before deployment.

After submitting a review request, navigate to Changes in the left navigation pane. The Proposed changes table shows each review that has run, including the proposed change description, its source, category, status, and when it was created. You can filter by category or status to find specific reviews, or search by name using the search bar. Choose any entry to open the full execution detail.

The Timeline tab shows the agent’s step-by-step reasoning process, including the tools it called, the dependencies it consulted, and the observations it made at each step. Each entry is timestamped, giving you a complete record of how the agent built its understanding of the change and reached its conclusion.

Choose the Report tab to see the final recommendation. The report opens with a summary header showing the recommended action, the number of critical issues found, the commit revision, and the number of files changed. The recommended action is either BLOCK, Proceed with Caution, or Safe to Release.

Below the summary header, the Analysis section explains why the recommendation was made, citing specific risks and the evidence the agent found to support its conclusion. The Issues section lists each finding by severity, giving you a prioritized view of what needs to be addressed before the change can proceed. The Recommendations section provides specific, actionable steps the developer can take to resolve each issue. Finally, the Changes section lists each file that was modified, with the type of change, the category it falls under, and a description of what was changed, so reviewers have a complete picture of what the change does before it merges.

You can also invoke the autonomous release testing feature directly from the chat interface. To run an autonomous release test on a web or API-based application, choose New chat and enter a query such as:

Run a release test on my application deployed at [application URL]

The agent generates a change-specific test plan and executes it in your provisioned environment. Results appear in Changes, where you can review the execution steps and a structured summary of what was tested.

Get started today
The release readiness review and autonomous release testing features for AWS DevOps Agent are available in preview. These features are available at no additional cost during preview in the US East (N. Virginia) Region. For pricing information on other AWS DevOps Agent features, visit the AWS DevOps Agent pricing page.

For configuration details, visit the AWS DevOps Agent user guide.

— Esra

AWS Security Agent adds threat modeling, Kiro power and Claude Code plugin, and more

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-security-agent-adds-threat-modeling-kiro-power-and-claude-code-plugin-and-more/

At re:Invent 2025, we previewed AWS Security Agent (now part of AWS Continuum), a frontier agent that proactively secures your applications throughout the development lifecycle across all your environments. You can perform on-demand penetration testing customized to your application, discovering and reporting security risks verified through exploitability testing.

Since the preview, we announced general availability for on-demand penetration testing and the preview of full repository code review that performs deep, context-aware security analysis of your entire codebase.

Today, we’re introducing more features based on customer feedback:

  • Code review updates (Preview) — You can now use pull request scanning with remediation, security requirements packs, and simulated validation. New integrations support GitHub, GitLab, Bitbucket, and Confluence.
  • Threat modeling (Preview) — AWS Security Agent analyzes your design documents or application source code, understands the full context of your application architecture and identifies threats with recommended mitigations using the STRIDE framework.
  • Kiro power, Claude Code plugin, and MCP integration — You can run code reviews, generate threat models, and remediate findings directly from your IDE, CLI, or any AI-powered IDE through an open MCP integration, with results surfacing inline without any context switching.

Let’s take a closer look at each launch!

Code review updates
You can now connect to GitLab and Bitbucket in addition to GitHub— supporting both SaaS and self-hosted versions, so you can trigger scans regardless of where code lives. You can also integrate Confluence to reference your existing documentation as context for reviews.

To get started, choose Enable code review or update your code review setting in the Security Agent console.

AWS Security Agent introduces deep, reasoning-based analysis on every pull request as well as full repository to identify complex vulnerabilities that go beyond pattern-matching. It checks against your organizational security requirements and common security risks to catch what other tools can’t. To get started, access the Security Agent web application and run your code review.

You’ll receive fix commits and remediation guidance directly in your GitHub, GitLab, or Bitbucket workflow, while your security teams configure the repositories to be monitored and intervene on critical issues. AWS Security Agent validates findings in simulated environments to demonstrate proof of exploitability. This embeds security expertise across all repositories, reducing security-related delays in the development pipeline.

To learn more about new code review features, visit Create a code review in the AWS Security Agent User Guide.

Design review updates
You can continuously validate your security requirements across every design and code review with managed compliance packs: AWS WAF, NIST CSF, PCI DSS, and AWS best practices, or import your own organizational requirements directly from internal documents or Confluence. Every finding maps back to your compliance posture, so teams stay audit-ready as they build.

To learn more, visit the design review documentation.

Threat modeling
AWS Security Agent generates threat models based on your design documentation or code repository, creates and build context about the application, including data flows, architecture, and trust boundaries. It maps out all components of your application, identifies potential threat actors and attack vectors, determines where weaknesses may exist, and prioritizes threats so you know what to address first.

To get started, choose Enable threat model and Connect source code repository in the Security Agent console.

To learn more, visit the threat modeling documentation.

Kiro power and Claude Code plugin for Security Agent
AWS Security Agent introduces a new Kiro power and Claude Code plugin (coming soon) and can be integrated with any AI IDE through an open MCP integration to secure your applications. You can trigger threat models and code reviews directly from your IDE, with results surfacing inline without any context switching.

To get started, install the Kiro power, and run your prompts. The Kiro power uses the AWS Security Agent MCP server. You can get started with the power by asking “Set up AWS Security Agent“. Kiro will check if you have an Agent Space and ask if you would like to use the existing one or create a new one.

With the Kiro power for Security Agent, you can catch vulnerabilities on every pull request as you build and scan an entire repository to surface accumulated risk by asking “Run a full security scan on this repo“. The Security Agent power includes an Agent hook to evaluate if a code review diff scan should be started after the Kiro agent has completed its turn. Before deploying to production, you can run a penetration test from your CLI to find what most scanners miss. Security Agent closes the loop by validating every finding and generating ready-to-implement code fixes.

You can pull the findings back into your development environment by asking “help me remediate my findings“. The Kiro power for AWS Security Agent will download findings to your local workspace, prioritize the most critical finding, and offer to start a bugfix spec session. You can iterate on fixing the findings using their familiar IDE with their existing tooling, steering, powers, and MCP servers.

You can also run threat models through the Kiro power in the IDE by asking “Build a threat model for this application“. The generated threat model is saved to .security-agent/threat_model.md. 

To learn more, visit the Kiro power for Security Agent.

Now available
AWS Security Agent understands the full security context across your software development lifecycle by covering design-time security (design reviews and threat modeling in preview), development-time security (code review in preview), and deployment-time security (penetration testing in GA), in a single, unified agentic offering. To learn more, visit the AWS Security Agent product page and the technical documentation.

These features are now available in AWS commercial Regions where AWS Security Agent is available. For Regional availability and the future roadmap, visit the AWS Capabilities by Region. For detailed pricing information and to access our 2-month free trial offer, please visit the AWS Security Agent pricing page.

Give it a try in the Security Agent console and send feedback to AWS re:Post for Security Agent or through your usual AWS Support contacts.
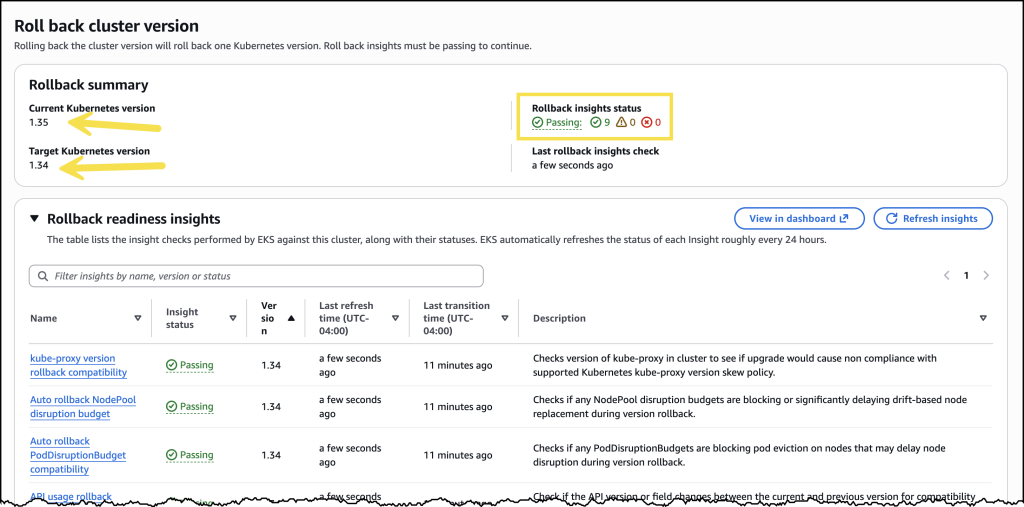
— Channy

Amazon S3 annotations: attach rich, queryable context directly to your objects

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/amazon-s3-annotations-attach-rich-queryable-context-directly-to-your-objects/

Today, we’re announcing a new metadata capability for Amazon Simple Storage Service (Amazon S3) called annotations, enabling you to attach rich, large-scale business context directly to your objects. You can store up to 1,000 named annotations per object, each up to 1 MB in size, totaling up to 1 GB per object, in flexible formats like JSON, XML, YAML, or plain text. You can modify or delete an annotation at any time, without re-writing your objects, making it easy to keep your object context current.

Organizations are building AI agents and autonomous workflows that need to find, understand, and act on data without human intervention. To support these agentic workflows, you need metadata that can evolve alongside the data, scale to petabytes of objects, and remain queryable without expensive retrieval.

With S3 annotations, you can store context such as AI-generated transcripts, content ratings, or technical specifications directly alongside your objects. Your context moves automatically with the object during copy, replication, and cross-region transfers, and S3 removes it when you delete the object. When you enable S3 Metadata, annotations automatically flow into fully managed annotation tables that you can query with Amazon Athena and other analytics engines.

Common use cases
Annotations solve complex metadata challenges across industries:

  • Media & Entertainment: Track transcripts, content moderation results, subtitle files, and licensing metadata as separate annotations on video assets, eliminating the need to synchronize metadata across multiple media asset management systems.
  • Financial Services: Attach AI-generated investment summaries and sentiment analysis to research documents, enabling autonomous research agents to discover relevant datasets through natural-language queries without maintaining separate metadata databases.
  • Life Sciences: Annotate clinical trial data with regulatory status, patient cohort details, and approval chains, making compliance audits faster while keeping full context accessible for archived data in Amazon S3 Glacier storage classes without retrieval charges.

How annotations address metadata challenges
Amazon S3 already supports several ways to describe your objects. System-defined metadata captures properties like size and storage class. Object tags support operational tasks like access control and lifecycle management. User-defined metadata lets you add small amounts of custom information at upload time.

While these capabilities work well for their intended purposes, they have limitations when you need to attach much richer context without building and maintaining separate metadata systems. Annotations address these needs by providing metadata capabilities at a fundamentally different scale and flexibility, offering mutable, queryable context per object compared to 10 immutable tags or 2 KB of headers.

Capability Max size Mutable? Best for
System-defined metadata Fixed No Object properties (size, storage class, creation time)
User-defined metadata 2 KB No (set at upload) Small custom key-value pairs
Object tags 10 tags, 128/256 characters per key/value Yes Access control, lifecycle rules, cost allocation
Annotations 1 GB (1,000 × 1 MB) Yes Rich business context (JSON, XML, YAML, plain text)

Today, metadata describing S3 objects often lives in separate databases or sidecar files, requiring complex synchronization workflows that can exceed data storage costs. When you enable S3 Metadata annotation tables, this context becomes queryable at scale through Amazon Athena. AI agents can discover your data through natural language with the S3 Tables MCP server, which provides a standardized interface for AI models to query your annotations. You can query annotations for objects in any storage class, without restoring the objects or paying retrieval charges.

Getting started with annotations
To start using annotations, make sure your AWS Identity and Access Management (IAM) policy or bucket policy grants permissions for the s3:PutObjectAnnotation and s3:GetObjectAnnotation actions. You can then add annotations to any existing or new S3 object using the PutObjectAnnotation API.

For example, a media company can attach technical specifications and AI-produced summaries to a video asset using the AWS Command Line Interface (AWS CLI):

# Create a JSON file with technical metadata
cat > mediainfo.json << 'EOF'
{"codec":"H.265","resolution":"3840x2160","audio_tracks":8,"frame_rate":29.97}
EOF

# Attach it as an annotation
aws s3api put-object-annotation \
  --bucket my-media-bucket \
  --key videos/documentary-2026.mp4 \
  --annotation-name mediainfo \
  --annotation-payload ./mediainfo.json
# Attach a plain-text AI-generated summary as a separate annotation
echo "A 90-minute nature documentary covering wildlife migration patterns across three continents, featuring aerial footage and underwater sequences. Languages: English, Spanish, Portuguese." > ai_summary.txt

aws s3api put-object-annotation \
  --bucket my-media-bucket \
  --key videos/documentary-2026.mp4 \
  --annotation-name ai_summary \
  --annotation-payload ./ai_summary.txt

These commands attach two separate annotations to the same video object. The mediainfo annotation stores structured technical specifications as JSON, while the ai_summary annotation stores a text description. Each annotation is identified by a unique name, and you can read and modify each one independently. With unique names for each annotation, you can use different annotations to support multiple concurrent enrichment workflows, for example, one team adding technical metadata while another team adds content classifications, without interfering with each other.

Retrieve a specific annotation using the GetObjectAnnotation API:

aws s3api get-object-annotation \
  --bucket my-media-bucket \
  --key videos/documentary-2026.mp4 \
  --annotation-name mediainfo \
  ./mediainfo-output.json

To see all annotations attached to an object, use the ListObjectAnnotations API:

aws s3api list-object-annotations \
  --bucket my-media-bucket \
  --key videos/documentary-2026.mp4

When you no longer need a specific annotation, remove it using the DeleteObjectAnnotation API:

aws s3api delete-object-annotation \
  --bucket my-media-bucket \
  --key videos/documentary-2026.mp4 \
  --annotation-name mediainfo

You can update an existing annotation at any time by calling PutObjectAnnotation again with the same annotation name. For large objects uploaded using multipart upload, attach annotations after completing the multipart upload using the PutObjectAnnotation API.

Querying annotations at scale with S3 Metadata tables
Attaching annotations to individual objects is useful, but the real power comes when you query across all your annotations at scale. When you enable S3 Metadata annotation tables on your bucket, S3 automatically indexes your annotations into a fully managed Apache Iceberg table, called an annotation table. You can query annotation tables with Amazon Athena or any Iceberg-compatible engine.

To enable annotation tables, use the S3 console or the CreateBucketMetadataConfiguration API. The following example creates a new metadata configuration with annotation tables enabled while keeping journal tables for change tracking and disabling the live inventory table:

{
  "JournalTableConfiguration": {
    "RecordExpiration": { "Expiration": "DISABLED" }
  },
  "InventoryTableConfiguration": { "ConfigurationState": "DISABLED" },
  "AnnotationTableConfiguration": {
    "ConfigurationState": "ENABLED",
    "Role": "arn:aws:iam::123456789012:role/S3MetadataAnnotationRole"
  }
}

This configuration tells S3 to automatically capture all your annotations in a queryable table. Once applied, any annotation you attach to objects in this bucket will appear in the table within approximately one hour.

If the bucket already has a metadata configuration, use the UpdateBucketMetadataAnnotationTableConfiguration API:

aws s3api update-bucket-metadata-annotation-table-configuration \
  --bucket my-media-bucket \
  --annotation-table-configuration '{"ConfigurationState":"ENABLED","Role":"arn:aws:iam::123456789012:role/S3MetadataAnnotationRole"}'

Once enabled, your annotations automatically flow into the annotation table. Journal tables update in near real time, while annotation tables refresh within an hour. Unlike traditional metadata tables that require predefined schemas, annotation tables automatically adapt to any JSON, XML, or YAML structure you write. Each annotation becomes a row in the table with its content stored in a text_value column, letting you query across all annotations without schema migrations.

If you enable annotation tables on a bucket that already has annotated objects, S3 automatically backfills existing annotations into the table. The backfill process runs in the background and can take several hours to days depending on the number of objects.

For example, to find all video assets with more than 8 audio tracks across your entire bucket using Amazon Athena:

SELECT DISTINCT bucket, object_key
FROM "s3tablescatalog/aws-s3"."b_my_media_bucket"."annotation"
WHERE name = 'mediainfo'
AND CAST(json_extract_scalar(text_value, '$.audio_tracks') AS INTEGER) > 8

This query scans the annotation table for all annotations named mediainfo, extracts the audio_tracks field from the JSON content, and returns objects where the count exceeds 8.

Or to find all objects that received new annotations in the last 24 hours through the journal table:

SELECT bucket, key, version_id, record_timestamp, annotation.name
FROM "s3tablescatalog/aws-s3"."b_my_media_bucket"."journal"
WHERE record_timestamp >= (current_date - interval '1' day)
AND annotation.name IS NOT NULL
AND record_type IN ('CREATE_ANNOTATION', 'DELETE_ANNOTATION')

This query uses the journal table to track annotation changes in near real time, which is ideal for building event-driven workflows that respond to new or deleted annotations.

You can also use natural language to search objects by their annotations using agents in Amazon SageMaker Unified Studio or any IDE with the S3 Tables MCP server. For example, asking “find all PG-rated movies with Spanish subtitles from 2023” returns results in seconds instead of the hours it would take querying multiple disconnected systems.

Get started today
You can start using Amazon S3 annotations today in all AWS Regions, including the AWS China Regions. Annotation tables are available in all AWS Regions where S3 Metadata is available.

Whether you’re building AI agents that need to discover data autonomously, managing petabytes of media assets with complex metadata, or tracking compliance context for archived datasets, annotations give you the scale and flexibility to attach rich metadata directly to your objects without managing separate systems.

Annotation storage is always billed at S3 Standard rates, even if the parent object is in S3 Glacier or another storage class. For full pricing details, visit the Amazon S3 pricing page.

To learn more and get started, visit the Amazon S3 Metadata overview page and the Amazon S3 documentation. Send feedback to AWS re:Post for S3 or through your usual AWS Support contacts.
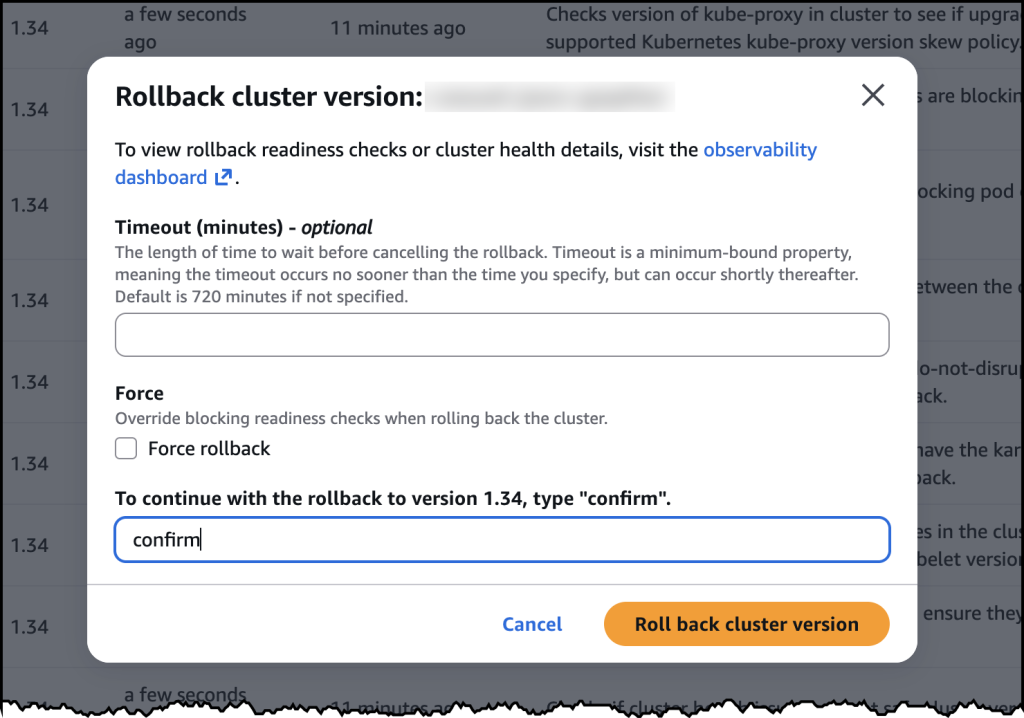
Daniel Abib

AWS WAF adds AI traffic monetization capability to help content owners charge AI bots for content access

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-waf-adds-ai-traffic-monetization-capability-to-help-content-owners-charge-ai-bots-for-content-access/

AWS WAF now includes AI traffic monetization capability that gives digital content owners and publishers a way to charge AI bots and agents for access to protected web content directly at the network edge. The capability helps content owners and publishers set per-request pricing by content path, bot category, or verification tier without modifying their origin infrastructure or writing application code. Content owners can define granular access policies per agent type, collect payments in stablecoins to their preferred wallet, and monitor revenue and bot activity from a single dashboard.

AI bot traffic now accounts for more than 50% of web traffic for many content providers, with AI-specific crawlers growing more than 300% year-over-year. Unlike traditional search engine crawlers, which index content and return measurable referral traffic back to publisher websites, AI bots consume the same content to generate summaries and responses in AI interfaces, with little to no traffic sent back to the original source. Publishers bear the infrastructure costs of serving that traffic without the page views, ad impressions, or subscription conversions that typically offset those costs. AWS WAF Bot Control already gives customers visibility into bot activity and the ability to block or rate-limit traffic, but setting pricing and collecting payment from AI agents has not been possible until now. AI traffic monetization is a new Bot Control capability that closes that gap, giving content owners and publishers a way to configure pricing rules directly through the AWS WAF console and collect payments from AI agents through third-party payment integrations, without building custom payment infrastructure or negotiating individual licensing agreements. Payment settlement and verification flows are provided by Coinbase’s x402 Facilitator. Integration with Stripe for direct account payments and Machine Payments Protocol (MPP) support is coming soon.
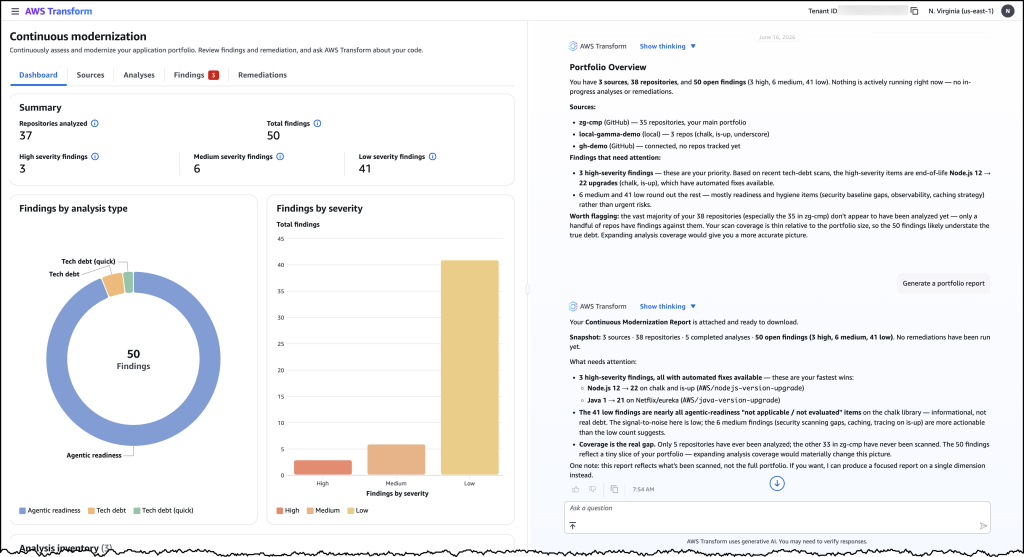
Getting Started with AI Traffic Monetization
Before configuring monetization, confirm that AWS WAF Bot Control is enabled at Common or Targeted level on the web ACL associated with your CloudFront distribution. Bot Control provides the agent classification that monetization rules depend on. If you have not set this up yet, visit Adding the AWS WAF Bot Control managed rule group to your web ACL documentation. In the AWS Management Console, go to WAF & Shield and choose Protection packs (web ACLs) in the left navigation pane to get started.

A protection pack is the core configuration unit for AI traffic monetization. It defines which content paths are monetized, what each agent verification tier is charged, which payment methods you accept, and what license terms apply. To create one, choose Create protection pack (web ACL).

In Tell us about your app, select one or more app categories that describe your content (for example, Content & publishing systems, E-commerce & transaction platforms, or Enterprise & business applications), and choose an App focus. AWS WAF uses these selections to recommend suitable security protections for your configuration.

In Select resources to protect, choose Add resources to associate regional or global resources such as CloudFront distributions with this protection pack. You can skip this step and add resources later.

In Choose initial protections, select from AWS WAF managed rule packages based on your app category and resource selections. You can also choose individual rules instead of packages.

In Name and describe, provide a name and optional description for the protection pack.

Optionally, expand Customize protection pack (web ACL) to configure additional settings including pricing tiers, payment methods, content scope, and license terms.

When finished, choose Create protection pack (web ACL).

Once your protection pack is in place, review the AI traffic analysis dashboard to understand the impact of AI bot traffic on your content before setting your pricing strategy. In the WAF & Shield console, go to AI traffic analysis in the left navigation pane. Select your protection pack (web ACL) from the dropdown to populate the dashboard.

The AI traffic analysis dashboard breaks down traffic into four categories visible in the bot traffic overview panel: All bot requests, AI bot requests, Verified AI bot traffic, and Unverified AI bot traffic. The dashboard surfaces infrastructure impact metrics including bandwidth consumed, estimated monthly cost, and peak request rates. A per-path heatmap shows which content paths receive the most AI bot activity by hour, giving you the data you need to make informed pricing decisions.

AWS WAF Bot Control classifies over 650 distinct AI bot and agent types including GPTBot, Claude-Web, and Perplexity-Bot, and assigns each a verification tier:

  • Verified — Agent identity confirmed through Web Bot Auth (WBA) Ed25519 cryptographic signature, or sourced from a documented IP range with a known set of user-agents and domain names.
  • Unverified — Agent recognized through user-agent matching, behavioral fingerprinting, and IP reputation, but identity not cryptographically confirmed.

Once you have reviewed your traffic patterns, return to Protection packs (web ACLs), select your protection pack from the list, and choose Configure AI monetization from the right panel to set pricing and access policies. Each protection pack defines the pricing, agent policies, accepted payment methods, and license terms that apply to a defined set of content paths. You can create multiple protection packs and apply different pricing to different content zones within the same distribution. Once created, associate the protection pack with your web ACL by opening the web ACL and choosing Add protection pack.

For each agent verification tier within the pack, you can assign one of six actions: Monetize (return a 402 with pricing), Allow (grant free access), Block (deny access entirely), Count (log without charging), CAPTCHA (present a puzzle to verify a human sender), or Challenge (run a silent check to verify the client is a browser, not a bot).

In the Edit monetization configuration page, configure the following:

Under Payment settlement, select one or more blockchain networks for stablecoin payments. Any wallet address on the supported networks is accepted, whether self-managed or hosted by a wallet provider such as Coinbase. For each network, provide your wallet address and set a Base price per page in USDC. You can add multiple networks using Add network. AWS does not process payments or take a fee on content revenue; disbursement is self-managed or managed by your wallet provider.

When a Monetize rule matches an incoming request, AWS WAF returns an HTTP 402 Payment Required response. The response body contains a machine-readable price manifest in JSON format using the x402 open protocol for machine-to-machine payments. The manifest includes the content price in USDC, accepted blockchain networks such as Base and Solana, the destination wallet address, the maximum payment timeout, and the payment scheme.

Any x402-compatible agent runtime can complete this flow autonomously. The client submits a signed payment authorization on their payment network of choice. AWS WAF verifies it, fetches the content, integrates with third-party facilitator services for settling the payment on-chain, and serves the response.

Note that the Monetize action is supported exclusively for web ACLs associated with Amazon CloudFront distributions. Adding a Monetize rule to a regional web ACL is not supported.

Since the Currency mode toggle is available directly in the monetization configuration page, you can switch between Real and Test mode at any time. Before going live, use test mode on non-production traffic to validate pricing, wallet configuration, and x402 payment flows. Note that test mode still enforces x402 payments, but those payments can be made on testnets such as Base Sepolia or Solana Devnet using test funds obtained from faucets such as faucet.circle.com. To activate test mode, toggle Currency mode to Test in your protection pack configuration. AWS WAF returns real price manifests and runs the full payment flow identically to production on the configured test chain. All events are logged with CurrencyMode: TEST. When satisfied with the configuration, toggle Currency mode back to Real to begin processing real payments.

Once you have switched Currency mode to Real, navigate to AI access monetization in the left navigation pane to track monetization outcomes in real time. Note that the AI access monetization dashboard only reflects activity from real currency mode and does not display test transactions.

The Revenue dashboard shows Total revenue, revenue broken down by Verified bots and Unverified bots, and Avg. per request. The Top revenue sources panel groups earnings by bot category, and the AI access patterns panel ranks content paths by revenue generated. Use the Settlements tab to reconcile payments by provider and review payment method distribution and failed payment attempts.

Now Available
AI traffic monetization is available now for Amazon CloudFront customers at no additional charge beyond standard AWS WAF pricing. The capability is available in all edge locations where AWS WAF web ACLs are associated with Amazon CloudFront distributions.

To learn more about AI traffic monetization, see the AWS WAF Developer Guide.

— Esra