Your privacy considerations are at the core of our compliance work at Amazon Web Services (AWS), and we are focused on the protection of your content while using AWS services. Our Spring 2022 SOC 2 Type I Privacy report is now available, which provides customers with a third-party attestation of our system and the suitability of the design of our privacy controls. The SOC 2 Privacy Trust Service Criteria (TSC), developed by the American Institute of Certified Public Accountants (AICPA) establishes the criteria for evaluating controls that relate to how personal information is collected, used, retained, disclosed, and disposed of. For more information about our privacy commitments supporting our SOC 2 Type 1 report, see the AWS Customer Agreement.
The scope of the Spring 2022 SOC 2 Type I Privacy report includes information about how we handle the content that you upload to AWS, and how it is protected in all of the services and locations that are in scope for the latest AWS SOC reports. The SOC 2 Type I Privacy report is available to AWS customers through AWS Artifact in the AWS Management Console.
As always, we value your feedback and questions. Feel free to reach out to the compliance team through the Contact Us page. If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security how-to-content, news, and feature announcements? Follow us on Twitter.
At Amazon Web Services (AWS), we’re committed to providing our customers with continued assurance over the security, availability and confidentiality of the AWS control environment. We’re proud to deliver the Spring 2022 System and Organizational (SOC) 1, 2 and 3 reports, which cover October 1, 2021 to March 31, 2022, to support our AWS customers’ confidence in AWS services.
The Spring 2022 SOC reports now include the Asia Pacific (Jakarta) Region, newly added to scope. The associated infrastructure supporting our in-scope products and services is also updated to reflect new edge locations, AWS Wavelength zones, and AWS Local Zones.
The Spring 2022 SOC reports include an additional 9 new services in scope, for a total of 150 services. See the full list on our Services in Scope by Compliance Program page.
Here are the 9 new services in scope for the Spring 2022 SOC reports:
AWS strives to bring services into scope of our compliance programs to help you meet your architectural and regulatory needs. If there are additional AWS services you would like to see added to the scope of our SOC reports or other compliance programs, reach out to your AWS representatives.
As always, we value your feedback and questions. Feel free to reach out to the team through the Contact Us page. If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security how-to-content, news, and feature announcements? Follow us on Twitter.
In the AWS Security Profile series, I interview some of the humans who work in Amazon Web Services Security and help keep our customers safe and secure. This interview is with Ely Kahn, principal product manager for AWS Security Hub. Security Hub is a cloud security posture management service that performs security best practice checks, aggregates alerts, and facilitates automated remediation.
How long have you been at AWS and what do you do in your current role?
I’ve been with AWS just over 4 years. I came to AWS through the acquisition of a company I co-founded called Sqrrl, which then became Amazon Detective. Shortly after the acquisition, I moved from the Sqrrl/Detective team and helped launch AWS Security Hub. In my current role, I’m the head of product for Security Hub, which means I lead our product roadmap and our product strategy, and I translate customer requirements into technical specifications.
How did you get started in the world of security?
My career started inside the U.S. federal government, first inside the Department of Homeland Security and, specifically, inside the Transportation Security Administration (TSA). At the time, the TSA had uncovered a vulnerability concerning boarding passes and the terrorist no-fly list. I was tasked with figuring out how to close that vulnerability, and I came up with a new way to embed a digital signature inside the barcode to help ensure the authenticity of the boarding pass. After that, people thought I was a cybersecurity expert, and I began working on a lot of cybersecurity strategy and policy at the Department of Homeland Security and then at the White House.
How do you explain your job to your non-tech friends?
I actually explain it the same way to technical and non-technical friends. I head up a service called Security Hub, which is designed to help you do a couple of different things. It helps you understand your security posture on AWS—what sort of risks you face and the most urgent security issues that you need to address across your AWS accounts. It also gives you the tools to improve your security posture and help you fix as many of those security issues as possible. We do that through three primary functions. First, we aggregate all of your security alerts into a standardized data format that’s available in one place. Second, we do our own automated security checks. We look at all the resources you’ve enabled on AWS and help check that those resources are configured in accordance with best practices that we define, and in alignment with various regulatory frameworks. Third, we help you auto-remediate and auto-respond to as many of those issues as possible.
What are you currently working on that you’re excited about?
Our number one priority with Security Hub is to expand coverage of the automated security checks that we provide. We have almost 200 automated security checks today covering several dozen AWS services. Over the next few years, we plan to expand this to more AWS services, which will add a large number of additional security checks. This is important because customers don’t want to have to write these security checks themselves. They want the one-click capability to turn on the checks—or controls, as we call them in Security Hub—and they should be automatically on in all of your accounts. They should only run if you’re using resources that are actually in-scope for those checks, and they should produce a security score to help you quickly understand the security posture of different accounts and of your organization as a whole.
What would you say is the coolest feature of Security Hub?
The coolest feature is probably the one that gets the least attention. It’s what we call our AWS Security Finding Format (ASFF). The ASFF is really just a data standard—it consists of over 1,000 JSON fields and objects, and it’s how you normalize all of your different security alerts. We’ve integrated 75 different services and partner products. The real advantage of Security Hub is that we automatically take all of those different alerts from all of those different integration partners and normalize them into this standardized data format, so that when you’re searching the findings you have a common set of fields to search against if you’re trying to do correlations. For example, you can imagine a situation where Amazon GuardDuty detects unusual activity in an Amazon Simple Storage Service (Amazon S3) bucket, one of our Security Hub checks detects that the bucket is open, and Amazon Macie determines that the bucket contains sensitive information. It’s much easier to do correlations for situations like this when the alerts from those different tools are in the same format. Similarly, building auto-response, auto-remediation workflows is much easier when all of your alerts are in the same format. One of our biggest customers at AWS called the ASFF the gold standard for how to normalize security alerts, which is something we’re super proud of.
As you mentioned, Security Hub integrates with a lot of other AWS services, like GuardDuty and Macie. How do you work with other service teams?
We work across AWS in a couple of different ways. We build out these integrations with other AWS services to either send or receive findings from those services. So, we receive findings from services like GuardDuty and Macie, and we send our findings to other services like AWS Trusted Advisor to give them the same view of security that we see in Security Hub. In general, we try to make it as simple and as low impact as possible because every service team is extremely busy. Wherever possible, we do the integration work and don’t put the onus of effort on the other service team.
The other way we work with other service teams is to formally define the best practices for that service. We have a security engineering team on Security Hub, and we partner with AWS Professional Services and their security consultants. Together, we have been working through the list of the most popular AWS services using a standard taxonomy of control categories to define security controls and best practices for that service. We then work with product managers and engineers on those service teams to review the controls we’re proposing, get their feedback, and then finally code them up as AWS Config rules before deploying them in Security Hub. We have a very well-honed process now to partner with the service teams to integrate with and define the security controls for each service.
Where do you suggest customers start with Security Hub if they are newer in their cloud journey?
The first step with Security Hub is just to turn it on across all of your accounts and AWS Regions. When you do, you’re likely going to see a lot of alerts. Don’t get overwhelmed with the number of alerts you see. Focus initially on the critical and high-severity alerts and work them as campaigns. Identify the owners for all open critical and high-severity alerts and start tracking burndown on a weekly basis. Coordinate with the leadership in your organization so you can identify which teams are keeping up with the alerts and which ones aren’t.
My favorite is one that I initially discounted: frugality. When I first joined AWS, what came to mind was Jeff Bezos using doors as desks. Although that’s certainly a component of frugality, I’ve found that for me, this principle means that we need to be frugal with each other’s time. There are so many competing demands on everyone’s time, and it’s extremely important in a place like AWS to be mindful of that. Make sure you’ve done your due diligence on something before you broadly ask the question or escalate.
What’s the thing you’re most proud of in your career?
There are two things. First is the acquisition of Sqrrl by AWS. I couldn’t have picked a better landing spot for Sqrrl and the team. I feel really lucky that I joined AWS through this acquisition. I’ve really learned a lot here in a short amount of time.
The other thing I’m especially proud of is to have been selected to do a stint through the White House National Security Council staff as the Department of Homeland Security representative to the Council. I sat in the cybersecurity directorate from 2009–2010 as part of that detail to the White House and got a chance to work in the West Wing and attend meetings in the Situation Room, which was just such a special experience.
If you had to pick an industry outside of security, what would you want to do?
This is pretty similar to security, but I got very close to going into the military. Out of high school, I was being recruited for lacrosse at the U.S. Air Force Academy. I had convinced myself that I wanted to go fly jets. I have the utmost respect for our military community, and I certainly could’ve seen myself taking that path.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
AWS Certificate Manager Private Certificate Authority (ACM PCA) is a highly available, fully managed private certificate authority (CA) service that allows you to create CA hierarchies and issue X.509 certificates from the CAs you create in ACM PCA. You can then use these certificates for scenarios such as encrypting TLS communication channels, cryptographically signing code, authenticating users, and more. But what happens if you decide to change your TLS endpoint or update your code signing entity? How do you revoke a certificate so that others no longer accept it?
In this blog post, we will cover two fully managed certificate revocation status checking mechanisms provided by ACM PCA: the Online Certificate Status Protocol (OCSP) and certificate revocation lists (CRLs). OCSP and CRLs both enable you to manage how you can notify services and clients about ACM PCA–issued certificates that you revoke. We’ll explain how these standard mechanisms work, we’ll highlight appropriate deployment use cases, and we’ll identify the advantages and downsides of each. We won’t cover configuration topics directly, but will provide you with links to that information as we go.
Certificate revocation
An X.509 certificate is a static, cryptographically signed document that represents a user, an endpoint, an IoT device, or a similar end entity. Because certificates provide a mechanism to authenticate these end entities, they are valid for a fixed period of time that you specify in the expiration date attribute when you generate a certificate. The expiration attribute is important, because it validates and regulates an end entity’s identity, and provides a means to schedule the termination of a certificate’s validity. However, there are situations where a certificate might need to be revoked before its scheduled expiration. These scenarios can include a compromised private key, the end of agreement between signed and signing organizations, user or configuration error when issuing certificates, and more. Although you can use certificates in many ways, we will refer to the predominant use case of TLS-based client-server implementations for the remainder of this blog post.
Certificate revocation can be used to identify certificates that are no longer trusted, and CRLs and OCSP are the standard mechanisms used to publish the revocation information. In addition, the special use case of OCSP stapling provides a more efficient mechanism that is supported in TLS 1.2 and later versions.
ACM PCA gives you the flexibility to use either of these mechanisms, or both. More importantly, as an ACM PCA administrator, the mechanism you choose to use is reflected in the certificate, and you must know how you want to manage revocation before you create the certificate. Therefore, you need to understand how the mechanisms work, select your strategy based on its appropriateness to your needs, and then create and deploy your certificates. Let’s look at how each mechanism works, the use cases for each, and issues to be aware of when you select a revocation strategy.
Certificate revocation using CRLs
As the name suggests, a CRL contains a list of revoked certificates. A CRL is cryptographically signed and issued by a CA, and made available for download by clients (for example, web browsers for TLS) through a CRL distribution point (CDP) such as a web server or a Lightweight Directory Access Point (LDAP) endpoint.
A CRL contains the revocation date and the serial number of revoked certificates. It also includes extensions, which specify whether the CA administrator temporarily suspended or irreversibly revoked the certificate. The CRL is signed and timestamped by the CA and can be verified by using the public key of the CA and the cryptographic algorithm included in the certificate. Clients download the CRL by using the address provided in the CDP extension and trust a certificate by verifying the signature, expiration date, and revocation status in the CRL.
CRLs provide an easy way to verify certificate validity. They can be cached and reused, which makes them resilient to network disruptions, and are an excellent choice for a server that is getting requests from many clients for the same CA. All major web browsers, OpenSSL, and other major TLS implementations support the CRL method of validating certificates.
However, the size of CRLs can lead to inefficiency for clients that are validating server identities. An example is the scenario of browsing multiple websites and downloading a CRL for each site that is visited. CRLs can also grow large over time as you revoke more certificates. Consider the World Wide Web and the number of invalidations that take place daily, which makes CRLs an inefficient choice for small-memory devices (for example, mobile, IoT, and similar devices). In addition, CRLs are not suited for real-time use cases. CRLs are downloaded periodically, a value that can be hours, days, or weeks, and cached for memory management. Many default TLS implementations, such as Mozilla, Chrome, Windows OS, and similar, cache CRLs for 24 hours, leaving a window of up to a day where an endpoint might incorrectly trust a revoked certificate. Cached CRLs also open opportunities for non-trusted sites to establish secure connections until the server refreshes the list, leading to security risks such as data breaches and identity theft.
Implementing CRLs by using ACM PCA
ACM PCA supports CRLs and stores them in an Amazon Simple Storage Service (Amazon S3) bucket for high availability and durability. You can refer to this blog post for an overview of how to securely create and store your CRLs for ACM PCA. Figure 1 shows how CRLs are implemented by using ACM PCA.
Figure 1: Certificate validation with a CRL
The workflow in Figure 1 is as follows:
On certificate revocation, ACM PCA updates the Amazon S3 CRL bucket with a new CRL.
Note: An update to the CRL may take up to 30 minutes after a certificate is revoked.
The client requests a TLS connection and receives the server’s certificate.
The client retrieves the current CRL file from the Amazon S3 bucket and validates it.
The refresh interval is the period between when an administrator revokes a certificate and when all parties consider that certificate revoked. The length of the refresh interval can depend on how quickly new information is published and how long clients cache revocation information to improve performance.
When you revoke a certificate, ACM PCA publishes a new CRL. ACM PCA waits 5 minutes after a RevokeCertificate API call before publishing a new CRL. This process exists to accommodate multiple revocation requests in a short time frame. An update to the CRL can take up to 30 minutes to propagate. If the CRL update fails, ACM PCA makes further attempts every 15 minutes.
CRLs also have a validity period, which you define as part of the CRL configuration by using ExpirationInDays. ACM PCA uses the value in the ExpirationInDays parameter to calculate the nextUpdate field in the CRL (the day and time when ACM PCA will publish the next CRL). If there are no changes to the CRL, the CRL is refreshed at half the interval of the next update. Clients may cache CRLs while they are still valid, so not all clients will have the updated CRL with the newly revoked certificates until the previous published CRL has expired.
Certificate revocation using OCSP
OCSP removes the burden of downloading the CRL from the client. With OCSP, clients provide the serial number and obtain the certificate status for a single certificate from an OCSP Responder. The OCSP Responder can be the CA or an endpoint managed by the CA. The certificate that is returned to the client contains an authorityInfoAccess extension, which provides an accessMethod (for example, OCSP), and identifies the OCSP Responder by a URL (for example, http://example-responder:<port>) in the accessLocation. You can also specify the OCSP Responder location manually in the CA profile. The certificate status response that is returned by the OCSP Responder can be good, revoked, or unknown, and is signed by using a process similar to the CRL for protection against forgery.
OCSP status checks are conducted in real time and are a good choice for time-sensitive devices, as well as mobile and IoT devices with limited memory.
However, the certificate status needs to be checked against the OCSP Responder for every connection, therefore requiring an extra hop. This can overwhelm the responder endpoint that needs to be designed for high availability, low latency, and protection against network and system failures. We will cover how ACM PCA addresses these availability and latency concerns in the next section.
Another thing to be mindful of is that the OCSP protocol implements OCSP status checks over unencrypted HTTP that poses privacy risks. When a client requests a certificate status, the CA receives information regarding the endpoint that is being connected to (for example, domain, IP address, and related information), which can easily be intercepted by a middle party. We will address how OCSP stapling can be used to address these privacy concerns in the OCSP stapling section.
Implementing OCSP by using ACM PCA
ACM PCA provides a highly available, fully managed OCSP solution to notify endpoints that certificates have been revoked. The OCSP implementation uses AWS managed OCSP responders and a globally available Amazon CloudFront distribution that caches OCSP responses closer to you, so you don’t need to set up and operate any infrastructure by yourself. You can enable OCSP on new or existing CAs using the ACM PCA console, the API, the AWS Command Line Interface (AWS CLI), or through AWS CloudFormation. Figure 2 shows how OCSP is implemented on ACM PCA.
Note: OCSP Responders, and the CloudFront distribution that caches the OCSP response for client requests, are managed by AWS.
Figure 2: Certificate validation with OCSP
The workflow in Figure 2 is as follows:
On certificate revocation, the ACM PCA updates the OCSP Responder, which generates the OCSP response.
The client requests a TLS connection and receives the server’s certificate.
The client sends a query to the OCSP endpoint on CloudFront.
Note: If the response is still valid in the CloudFront cache, it will be served to the client from the cache.
If the response is invalid or missing in the CloudFront cache, the request is forwarded to the OCSP Responder.
The OCSP Responder sends the OCSP response to the CloudFront cache.
CloudFront caches the OCSP response and returns it to the client.
The ACM PCA OCSP Responder generates an OCSP response that gets cached by CloudFront for 60 minutes. When a certificate is revoked, ACM PCA updates the OCSP Responder to generate a new OCSP response. During the caching interval, clients continue to receive responses from the CloudFront cache. As with CRLs, clients may also cache OCSP responses, which means that not all clients will have the updated OCSP response for the newly revoked certificate until the previously published (client-cached) OCSP response has expired. Another thing to be mindful of is that while the response is cached, a compromised certificate can be used to spoof a client.
Certificate revocation using OCSP stapling
With both CRLs and OCSP, the client is responsible for validating the certificate status. OCSP stapling addresses the client validation overhead and privacy concerns that we mentioned earlier by having the server obtain status checks for certificates that the server holds, directly from the CA. These status checks are periodic (based on a user-defined value), and the responses are stored on the web server. During TLS connection establishment, the server staples the certificate status in the response that is sent to the client. This improves connection establishment speed by combining requests and reduces the number of requests that are sent to the OCSP endpoint. Because clients are no longer directly connecting to OCSP Responders or the CAs, the privacy risks that we mentioned earlier are also mitigated.
Implementing OCSP stapling by using ACM PCA
OCSP stapling is supported by ACM PCA. You simply use the OCSP Certificate Status Response passthrough to add the stapling extension in the TLS response that is sent from the server to the client. Figure 3 shows how OCSP stapling works with ACM PCA.
Figure 3: Certificate validation with OCSP stapling
The workflow in Figure 3 is as follows:
On certificate revocation, the ACM PCA updates the OCSP Responder, which generates the OCSP response.
The client requests a TLS connection and receives the server’s certificate.
In the case of server’s cache miss, the server will query the OCSP endpoint on CloudFront.
Note: If the response is still valid in the CloudFront cache, it will be returned to the server from the cache.
If the response is invalid or missing in the CloudFront cache, the request is forwarded to the OCSP Responder.
The OCSP Responder sends the OCSP response to the CloudFront cache.
CloudFront caches the OCSP response and returns it to the server, which also caches the response.
The server staples the certificate status in its TLS connection response (for TLS 1.2 and later versions).
OCSP stapling is supported with TLS 1.2 and later versions.
Selecting the correct path with OCSP and CRLs
All certificate revocation offerings from AWS run on a highly available, distributed, and performance-optimized infrastructure. We strongly recommend that you enable a certificate validation and revocation strategy in your environment that best reflects your use case. You can opt to use CRLs, OCSP, or both. Without a revocation and validation process in place, you risk unauthorized access. We recommend that you review your business requirements and evaluate the risk profile of access with an invalid certificate versus the availability requirements for your application.
In the following sections, we’ll provide some recommendations on when to select which certificate validation and revocation strategy. We’ll cover client-server TLS communication, and also provide recommendations for mutual TLS (mTLS) authentication scenarios.
Recommended scenarios for OCSP stapling and OCSP Must-Staple
If your organization requires support for TLS 1.2 and later versions, you should use OCSP stapling. If you want to reduce the application availability risk for a client that is configured to fail the TLS connection establishment when it is unable to validate the certificate, you should consider using the OCSP Must-Staple extension.
OCSP stapling
If your organization requires support for TLS 1.2 and later versions, you should use OCSP stapling. With OCSP stapling, you reduce your client’s load and connectivity requirements, which helps if your network connectivity is unpredictable. For example, if your application client is a mobile device, you should anticipate network failures, low bandwidth, limited processing capacity, and impatient users. In this scenario, you will likely benefit the most from a system that relies on OCSP stapling.
Although the majority of web browsers support OCSP stapling, not all servers support it. OCSP stapling is, therefore, typically implemented together with CRLs that provide an alternate validation mechanism or as a passthrough for when the OCSP response fails or is invalid.
OCSP Must-Staple
If you want to rely on OCSP alone and avoid implementing CRLs, you can use the OCSP Must-Staple certificate extension, which tells the connecting client to expect a stapled response. You can then use OCSP Must-Staple as a flag for your client to fail the connection if the client does not receive a valid OCSP response during connection establishment.
Recommended scenarios for CRLs, OCSP (without stapling), and combinational strategies
If your application needs to support legacy, now deprecated protocols such as TLS 1.0 or 1.1, or if your server doesn’t support OCSP stapling, you could use a CRL, OCSP, or both together. To determine which option is best, you should consider your sensitivity to CA availability, recently revoked certificates, the processing capacity of your application client, and network latency.
CRLs
If your application needs to be available independent of your CA connectivity, you should consider using a CRL. CRLs are much larger files that, from a practical standpoint, require much longer cache times to be of use, but they will be present and available for verification on your system regardless of the status of your network connection. In addition, the lookup time of a certificate within a CRL is local and therefore shorter than a network round trip to an OCSP Responder, because there are no network connection or DNS lookup times.
OCSP (without stapling)
If you are sensitive to the processing capacity of your application client, you should use OCSP. The size of an OCSP message is much smaller compared to a CRL, which allows you to configure shorter caching times that are better suited for your risk profile. To optimize your OCSP and OCSP stapling process, you should review your DNS configuration because it plays a significant role in the amount of time your application will take to receive a response.
For example, if you’re building an application that will be hosted on infrastructure that doesn’t support OCSP stapling, you will benefit from clients making an OCSP request and caching it for a short period. In this scenario, your application client will make a single OCSP request during its connection setup, cache the response, and reuse the certificate state for the duration of its application session.
Combining CRLs and OCSP
You can also choose to implement both CRLs and OCSP for your certificate revocation and validation needs. For example, if your application needs to support legacy TLS protocols while providing resiliency to network failures, you can implement both CRLs and OCSP. When you use CRLs and OCSP together, you verify certificates primarily by using OCSP; however, in case your client is unable to reach the OCSP endpoint, you can fail over to an alternative validation method (for example, CRL). This approach of combining CRLs and OCSP gives you all the benefits of OCSP mentioned earlier, while providing a backup mechanism for failure scenarios such as an unreachable OCSP Responder, invalid response from the OCSP Responder, and similar. However, while this approach adds resilience to your application, it will add management overhead because you will need to set up CRL-based and OCSP-based revocation separately. Also, remember that clients with reduced computing power or poor network connectivity might struggle as they attempt to download and process the CRL.
Recommendations for mTLS authentication scenarios
You should consider network latency and revocation propagation delays when optimizing your server infrastructure for mTLS authentication. In a typical scenario, server certificate changes are infrequent, so caching an OCSP response or CRL on your client and an OCSP-stapled response on a server will improve performance. For mTLS, you can revoke a client certificate at any time; therefore, cached responses could introduce the risk of invalid access. You should consider designing your system such that a copy of a CRL for client certificates is maintained on the server and refreshed based on your business needs. For example, you can use S3 ETags to determine whether an object has changed, and flush the server’s cache in response.
Conclusion
This blog post covered two certificate revocation methods, OCSP and CRLs, that are available on ACM PCA. Remember, when you deploy CA hierarchies for public key infrastructure (PKI), it’s important to define how to handle certificate revocation. The certificate revocation information must be included in the certificate when it is issued, so the choice to enable either CRL or OCSP, or both, has to happen before the certificate is issued. It’s also important to have highly available CRL and OCSP endpoints for certificate lifecycle management. ACM PCA provides a highly available, fully managed CA service that you can use to meet your certificate revocation and validation requirements. Get started using ACM PCA.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
This blog post outlines how to use your existing Microsoft Active Directory (AD) to reliably authenticate access to your Amazon Web Services (AWS) accounts, infrastructure running on AWS, and third-party applications. The architecture we describe is designed to be highly available and extends access to your existing AD to AWS, enabling your users to use their existing credentials to access authorized AWS resources and applications.
Many customers rely on AD as their single source of truth for IT identity management. HR automation processes are often already in place to automatically add, update, and remove employee access within an organization’s AD as staffing changes occur. Using a single source of truth as the basis for all authentication and authorization, both on-premises and in the cloud, makes it easier to manage access across multiple applications and services, because you are creating, managing, and revoking access from a single location. For example, if someone leaves your organization, you can revoke access for all applications and services (including AWS accounts) from one location. Additionally, this reduces risks associated with stranded or forgotten credentials, or users needing to remember multiple different sets of credentials.
Microsoft Active Directory (AD) is deployed on Microsoft Windows Server servers called domain controllers, which replicate the contents of the directory between the domain controllers that are hosting the AD domain. Multiple domain controllers are deployed within a domain to improve the availability and performance of the directory. The AD infrastructure should be designed to provide sufficiently high levels of availability and performance, because it governs access to your organization’s IT resources. This typically requires the placement of at least one domain controller in every customer hosting location, because the lack of availability of your identity store is likely to cause authentication and authorization failures, which in turn prevent access to resources.
These design principles align with the Security Pillar of the AWS Well-Architected Framework, which is focused on implementing a strong identity foundation. The Security Pillar guidance states that you should centralize identity management and aim to eliminate reliance on long-term static credentials. By using your existing AD, you can benefit from centralized identity management and your existing group-based permissions for access to your AWS accounts. Applications that are running on domain-joined servers can use their AD service account credentials when they access other domain-joined resources, which removes the need for those credentials to be stored in application configuration files. As your AWS usage grows, it is important to give serious consideration to effective identity management, both for access to AWS and AWS resources, and for your instances that are running on AWS.
By extending your existing Active Directory to AWS, you can continue to use your existing Active Directory user credentials and group policies to manage your Microsoft Windows Server servers, whether those servers are running on-premises or on AWS, and extend these capabilities to authenticate and authorize access to the AWS Management Console and third-party applications.
This post covers networking requirements and connectivity setup to enable network connectivity to your on-premises AD; the approach to extending your AD to AWS; integrating AWS Single Sign-On with your AD; and joining Amazon Elastic Compute Cloud (Amazon EC2) instances to AD. As part of the setup, you will add additional domain controllers running on Amazon EC2 instances to your existing AD, for availability and latency reasons. You will also build a resource forest to enable your existing AD identities to access AD-integrated AWS services and resources. This enables you to have a highly available single identity source as the source of truth for your user authentication.
Networking prerequisites to extend your Active Directory to AWS
To enable Active Directory–related network communication, network connectivity needs to be established between your on-premises network and your AWS environment. You need to ensure there is connectivity between the on-premises network that is hosting your existing domain controllers and the Amazon Virtual Private Cloud (Amazon VPC) VPC that will host your AD infrastructure on AWS. Typically, hybrid network connectivity is configured within a network account within your organization, where the multiple AWS accounts within your organization are managed by using AWS Organizations. This network account effectively sits between your on-premises network and the resources, including the AD infrastructure, that are deployed in AWS.
You can provide connectivity between your on-premises network and your network account by using AWS Site-to-Site VPN or AWS Direct Connect connections. For an overview of the options to connect your on-premises network to AWS, refer to Amazon Virtual Private Cloud Connectivity Options. The necessary routing and firewall rules need to be configured to allow connectivity between these subnets and the on-premises network that is hosting your existing domain controllers. AWS recommends that you have highly resilient, fault-tolerant connectivity with dynamic routing between your on-premises network and your AWS network. You can achieve high resiliency through the use of redundant AWS Direct Connect connections, or, for less critical workloads, a VPN connection might offer sufficient resilience.
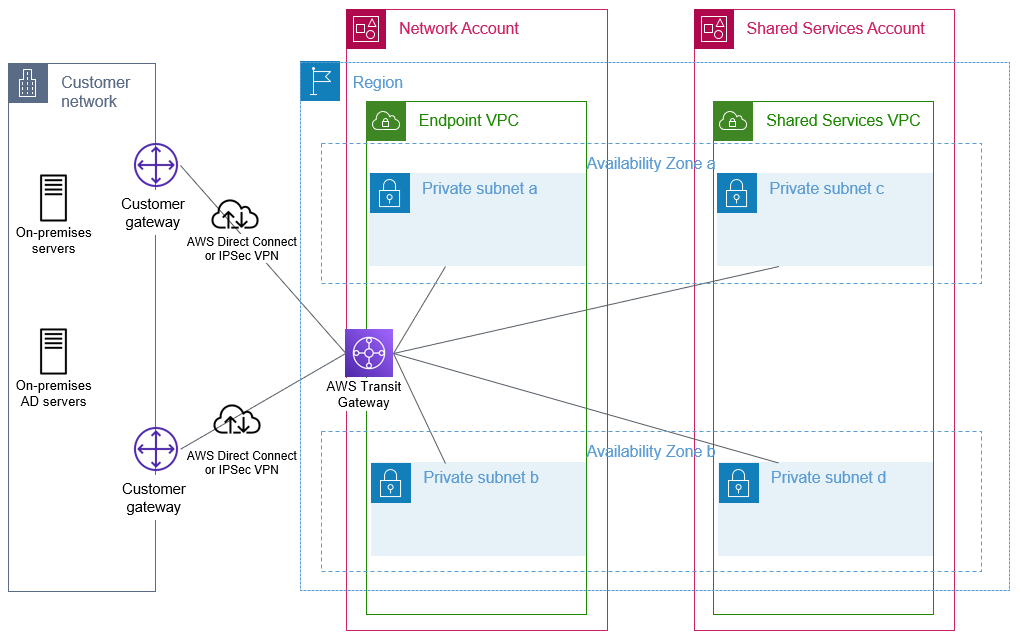
We recommend AWS Transit Gateway to provide connectivity between your AWS accounts. A transit gateway will be in your network account and then shared with your other AWS accounts that have VPCs that require access to on-premises networks or other VPCs. This enables a hub and spoke network architecture, which is used to provide connectivity both between your VPCs as needed and between your VPCs and your on-premises network. You will create a VPC, which we will refer to within this blog as the endpoint VPC, with subnets across two Availability Zones, within the network account. This endpoint VPC will be used later by Amazon Route 53 outbound endpoints for DNS resolution of AD-hosted DNS zones. Other documentation might refer to this endpoint VPC by alternative names, such as outbound VPC or egress VPC.
Your AD infrastructure that is running on AWS is typically deployed within a shared services account, sometimes referred to as an operations account. Within this shared services account, you will create a shared services VPC with at least two subnets within different Availability Zones to host your domain controller infrastructure on AWS. Your domain controller availability is increased when your architecture is configured to use multiple Availability Zones. You will attach this shared services VPC to the transit gateway that is shared from your network account. This VPC attachment provides connectivity between this VPC and your on-premises network through the transit gateway and network account. You will need to configure the subnet route table(s) and transit gateway route table(s) appropriately to provide IP connectivity between the shared services VPC and your on-premises network.
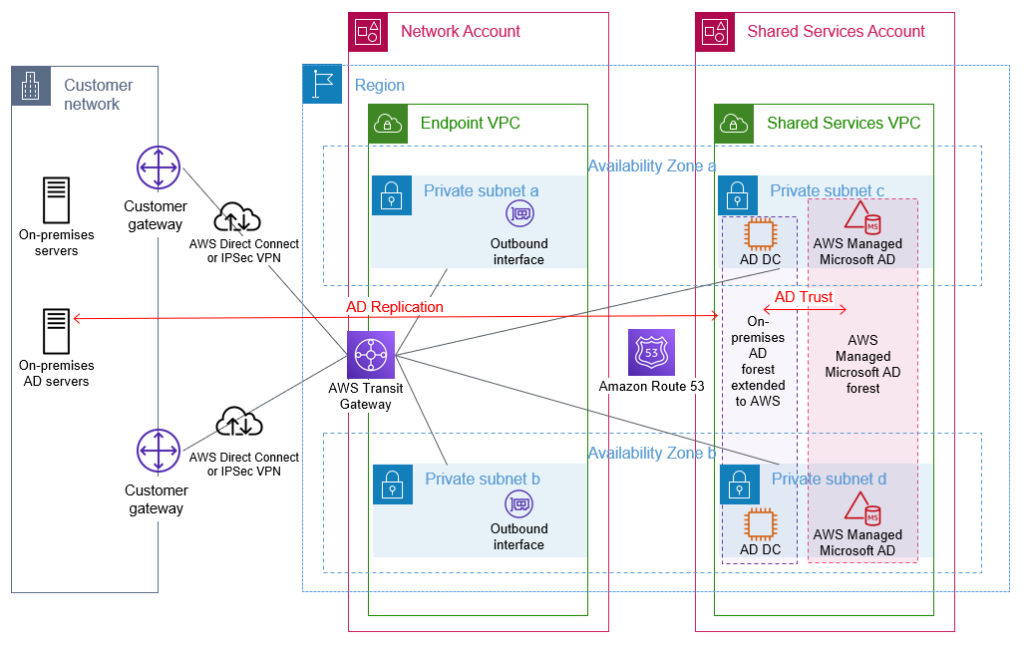
The sample architecture shown in Figure 1 illustrates the use of a transit gateway with two AWS Direct Connect connections to provide resilient connectivity between an on-premises network, the network account, and a VPC within the shared services account.
Figure 1: Foundational network connectivity between on-premises and AWS VPCs
Active Directory relies heavily on Domain Name System (DNS) services and typically hosts its own DNS services on domain controllers. To establish name resolution of your AD-hosted DNS domains from within your VPCs, you should use Route 53 Resolver with outbound resolver endpoints and forwarding rules. Forwarding rules specify the domain name queries to forward from your VPCs to DNS servers that are authoritative for your AD DNS names. The queries will be forwarded through the outbound endpoints. The outbound endpoints will be configured in the network account on the endpoint VPC, and use the previously configured network connectivity to communicate with your existing DNS servers. You will configure your existing DNS servers as targets in the forwarding rules. Configuring Route 53 Resolver with the appropriate forwarding rules will help to enable seamless DNS resolution between your on-premises and AWS hosted resources. You need to share the Route 53 Resolver rules with your organization so that they can be used by your other AWS accounts. These shared rules are then associated with your VPCs, which need to be able to resolve names within AD-hosted DNS domains. Refer to the AWS Hybrid DNS with Active Directory technical guide for detailed step-by-step configuration guidance.
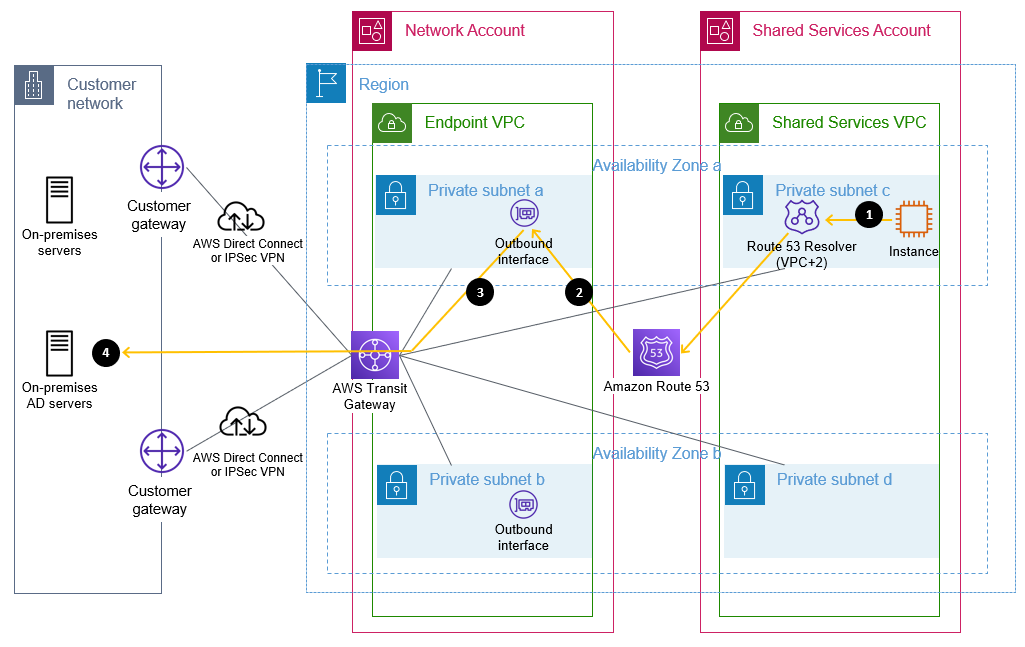
Figure 2 shows a sample flow of a DNS query from an Amazon Elastic Compute Cloud (Amazon EC2) instance through Route 53 Resolver and an outbound interface when resolving an on-premises domain name that matches a forwarding rule. In this example, the domain controllers are also the DNS servers, but splitting the DNS and AD servers is also fully supported.
Figure 2: Flow of a DNS query matching a forwarding rule through a Route 53 outbound endpoint
The flow is as follows:
An Amazon EC2 instance sends a DNS request for an internal name, such as ad.example.com, to the Route 53 Resolver address within the VPC.
Route 53 matches this query against a forwarding rule and directs the query through the configured outbound interface.
The query is sent from the outbound interface towards the target IP address, configured in the forwarding rule, of a server that is authoritative for the domain name.
This target DNS server receives the query and responds.
To extend your existing AD to AWS, domain controllers on Amazon EC2 instances are required, because AWS Managed Microsoft AD does not support being added to an existing forest. An AWS Managed Microsoft AD resource forest is required to enable integration with AWS services that offer AD integration. This is discussed in more detail in the following sections.
Extend your on-premises AD to AWS
Your first step is to build additional AD domain controllers for your existing AD domain(s) on Amazon EC2 instances that are running Microsoft Windows Server. You would then manage these domain controllers along with your existing domain controllers. By running additional domain controllers within AWS, you remove dependencies on network links and improve reliability and performance of your directory for infrastructure that is running within AWS. Communication between the domain controllers and other domain-joined resources within AWS is designed to remain within the AWS Region. AWS recommends that a minimum of two domain controllers, spread across multiple Availability Zones for resilience, are deployed. You should deploy the domain controllers into the subnets within the shared services VPC.
Depending on your capacity planning considerations and availability goals, you may choose to deploy more than two domain controllers. The number of users, servers, and applications that access your directory will influence the required number of domain controllers. Security considerations, including the required TCP/IP ports, and management options are discussed in the blog post Securely extend and access on-premises Active Directory domain controllers in AWS.
These new domain controllers will be in a new AD site, which includes all your VPC CIDR blocks within your chosen AWS Region. In Active Directory, a site represents a group of IP subnets that are connected with fast and highly reliable network connectivity. Site information is used to locate domain controllers closest to the client, to reduce latency and unnecessary network traffic. AWS recommends that your VPCs within an AWS Region belong to the same new Active Directory site, consisting only of your IP ranges within the chosen AWS Region, and that consistent site names are used in all AD forests that are connected by trusts. Further details are available in the section Designing Active Directory sites and services topology in Active Directory Domain Services on AWS and in Designing the Site Topology.
Update targets in Route 53 Resolver rules
After you have deployed AD-integrated DNS servers to these domain controllers and opened the required TCP/IP ports on the associated security groups, you can update the targets in your Route 53 Resolver forwarding rules to use the IP addresses of these servers. This will improve performance and reliability of DNS resolution, by removing the need for DNS resolution traffic to flow between AWS and on-premises infrastructure.
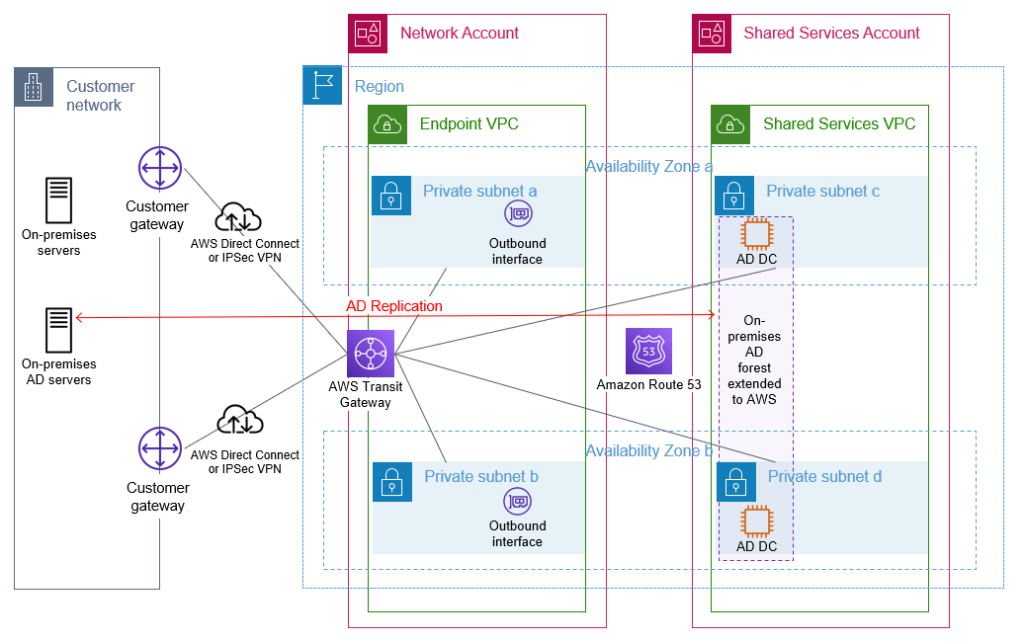
Figure 3 shows Amazon EC2 instances that are configured as AD domain controllers within a shared services VPC. After they are configured, these domain controllers will replicate with the on-premises domain controllers, using the connectivity that is provided through the transit gateway.
Figure 3: On-premises AD extended to AWS by deploying additional domain controllers
Build a resource forest for AWS hosted infrastructure and applications
When you select and launch this directory type, it is created as a highly available pair of domain controllers that are connected to your virtual private cloud (VPC). The domain controllers run in different Availability Zones in your choice of AWS Region. Host monitoring and recovery, data replication, snapshots, and software updates are automatically configured and managed for you. AWS Managed Microsoft AD is available in Standard and Enterprise Editions.
The AWS Managed Microsoft AD will be shared with your accounts within your organization to enable your other AWS accounts to access this directory and benefit from the features and services outlined previously.
With correct AD site configuration in both forests, communication between the AWS Managed Microsoft AD domain controllers and other domain-joined resources within AWS, and your existing domain’s domain controllers, remains within the chosen AWS Region. This is designed to keep your data within AWS in the country of your chosen AWS Region, to help to address possible data residency concerns.
An example of this architecture is depicted in Figure 4.
Figure 4: AWS Managed Microsoft AD resource forest with trust to on-premises AD
Manage access to your AWS accounts
AWS Single Sign-On (AWS SSO) enables you to centrally manage access across your AWS organization. You can choose to manage access just to your AWS accounts, or to your cloud applications as well. You can create user identities directly in AWS SSO, access your existing identifies by connecting AWS SSO to your existing Active Directory domain, or you can federate them from your Active Directory Federation Services (AD FS) or a standards-based identity provider, such as Okta Universal Directory or Azure AD. Your workforce users get a user portal to access all of their assigned AWS accounts or cloud applications. AWS SSO can be flexibly configured to run alongside or replace AWS account access management through AWS Identity and Access Management (IAM).
Identity federation is a system of trust between two parties for the purpose of authenticating third parties, such as users, and conveying information that is needed to authorize their access to resources. In this system, an identity provider (IdP) is responsible for user authentication, and a service provider (SP), such as a service or an application, controls access to resources. AWS SSO automates the setup of the identity federation that is used to provide authorized users access to your AWS accounts. AWS SSO is acting as an IdP when AWS SSO is connected to your AD and used to give access to your AWS accounts.
Although you can create users and groups directly within AWS SSO, a best practice is to use your existing identity single source of truth to simplify user and permission management. Connecting AWS SSO through to your Active Directory, which has been extended to AWS, will allow authentication of users for access to your AWS accounts to take place entirely within the AWS Region. This practice is designed to reduce dependencies on hybrid networking and resources located on-premises or in other hosting locations.
You should enforce secure access to the user portal, AWS SSO integrated apps, and the AWS CLI by enabling multi-factor authentication (MFA). AWS SSO MFA supports various MFA types, including client-side authenticator apps, security keys, and built-in authenticators. Using MFA is recommended as part of configuring strong sign-in mechanisms.
Connect AWS SSO to your Active Directory
You can connect AWS SSO to your Active Directory on AWS by using AD Connector, or through an AWS Managed Microsoft AD. Using AD Connector is often the primary mechanism considered by customers, but given the lack of support for multi-domain environments as used in this post, this blog post recommends using AWS Managed Microsoft AD.
When you use AWS Managed Microsoft AD with AWS SSO, AWS SSO requires two-way trusts to be in place between this AWS Managed Microsoft AD forest and any other forest that contains the user identities that will authenticate through AWS SSO.
Before AWS SSO supported delegated administration, AWS SSO had to be configured within the management account of your AWS organization, and required the connected AWS Managed Microsoft AD directory to also be within your organization’s management account.
With the announcement of AWS SSO delegated administration support, AWS SSO and the connected AWS Managed Microsoft AD can be configured in an account other than your management account. This post recommends using your shared services account as the AWS SSO delegated administration account. Doing so will enable AWS SSO to use the AWS Managed Microsoft AD that you configured within the shared services account in the preceding Build a resource forest for AWS hosted infrastructure and applications section.
This follows the AWS guidance to avoid deploying workloads to the organization’s management account and to limit access to the management account. Using a delegated administration account for AWS SSO reduces the need for regular access to the management account.
From within your management account, your shared services account needs to be registered as the AWS SSO delegated administration account. You can then configure and manage AWS SSO from within your shared services account. The AWS SSO delegated administration account can manage permissions across your organization, apart from assigning permissions to access the management account. Assignment of permissions to access the management account through AWS SSO needs to be configured from within the management account itself.
Permission sets are a way to define permissions centrally in AWS SSO so that they can be applied to all your AWS accounts. After you have created your permission sets, you will assign them to your Active Directory groups to grant access to the respective AWS accounts, using the defined permission set persona. Your users will then use the AWS SSO user portal to authenticate with their AD credentials and can choose which of the assigned AWS accounts and personas they wish to access. Users can configure AWS CLI to use AWS SSO to access the roles they have been assigned.
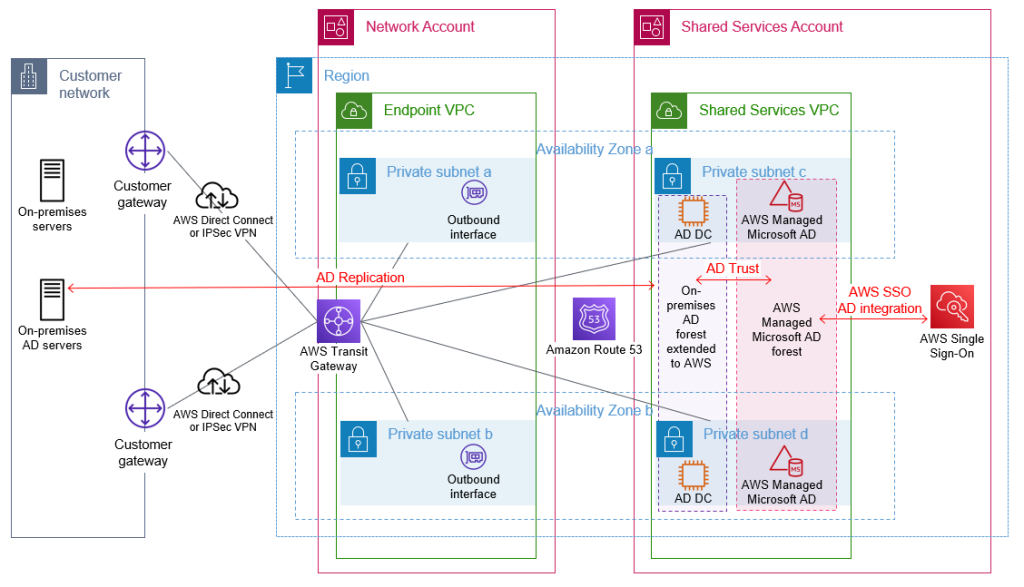
Figure 5 shows the complete architecture covered in this blog post. The diagram includes AWS SSO within the shared services account connected to the AWS Managed Microsoft AD that is used to provide access to the forests that contain your user identities.
Figure 5: Complete AD architecture with trusts and AWS SSO using AD as the identity source
Access domain-joined infrastructure resources
By joining your Windows Server servers to your Active Directory resource domain, you can centralize the management of your servers by using native Microsoft tooling. Joining your Amazon EC2 Windows instances to your domain enables you to continue using existing tools, such as group policies, to manage your server estate both on-premises and in AWS.
VPCs with workloads that need to be domain joined, to access on-premises networks, or to access other VPCs will need appropriate network connectivity and DNS configuration in place. You can enable network connectivity between workload VPCs and the shared services VPC and other on-premises networks by attaching your VPCs to the transit gateway shared from the networking account. You can enable DNS resolution of your AD domains by attaching the Route 53 Resolver rules, shared from the networking account, to your workload VPCs.
Join instances to your AD domain
Amazon EC2 Windows instances can be manually or seamlessly joined to your resource domain. Manually joining an instance involves the same steps that you would follow on-premises. Seamlessly joining instances requires the AWS Systems Manager agent, which is installed by default in AWS provided Windows AMIs, on the Amazon EC2 instance and an attached instance profile with sufficient permissions. This instance profile should include the AmazonSSMManagedInstanceCore and AmazonSSMDirectoryServiceAccess policies.
In order to join the domain, either manually or seamlessly, the Amazon EC2 instance must be able to resolve the DNS name for your AD domain. This DNS resolution was enabled by the attachment of the correctly configured shared Route 53 Resolver rules to the workload VPCs. Seamlessly joining instances to the domain also requires that your shared services account AWS Managed Microsoft AD directory be shared with the workload account that contains the Amazon EC2 instances.
After your instances are joined to the domain, applications running on the servers will be able to access other domain-joined resources, if authorized by AD, through the connectivity that is provided by the transit gateway attachment on the workload VPC.
Applications that need to access AWS resources that are not domain joined, such as objects in Amazon Simple Storage Service (Amazon S3), should make use of temporary credentials associated with the attached instance profile to access AWS resources. By using these IAM temporary credentials, you can avoid using static long-term credentials. When an application requires access to credentials or other secrets, and cannot use AD or IAM temporary credentials, such as for database logins or for third-party API tokens, use a service designed to handle management of secrets, such as AWS Secrets Manager. See the AWS Well-Architected Security Pillar Identity Management documentation for further guidance.
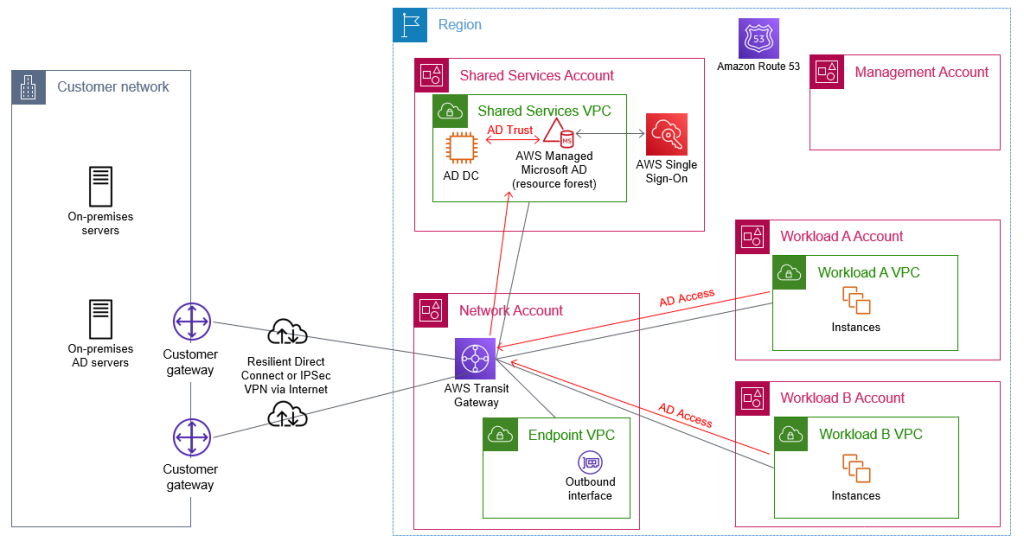
Figure 6 shows Active Directory access through the transit gateway. The Route 53 forwarding rules, which are shared from the shared services account, are associated with the workload VPCs to enable DNS resolution of Active Directory–integrated DNS domains. Not shown in the diagram is the sharing of the AWS Managed Microsoft AD for the resource forest with the workload accounts.
Figure 6: Flow of AD network traffic through the transit gateway within the network account
Access applications and third-party services
You might have existing applications that rely on Active Directory or LDAP for user authentication. When you extend your Active Directory environment to AWS, these existing applications can be deployed to your AWS environment, and they will be able to authenticate the users of the application against your AD.
You might already be using a third-party identity provider, such as Azure AD or Okta, to provide your users with access to AWS services such as AWS Client VPN or to third-party business applications such as those on the AWS SSO Cloud applications page. These third-party identity providers will typically offer an agent to replicate or synchronize necessary user information from your Active Directory to their service, in order to offer federated authentication for your users. Using these agents to replicate from your existing Active Directory means that you are still using your Active Directory as the single source of truth. To ensure reliable authentication, you should follow the vendor’s recommendations for the high-availability setup of their agent.
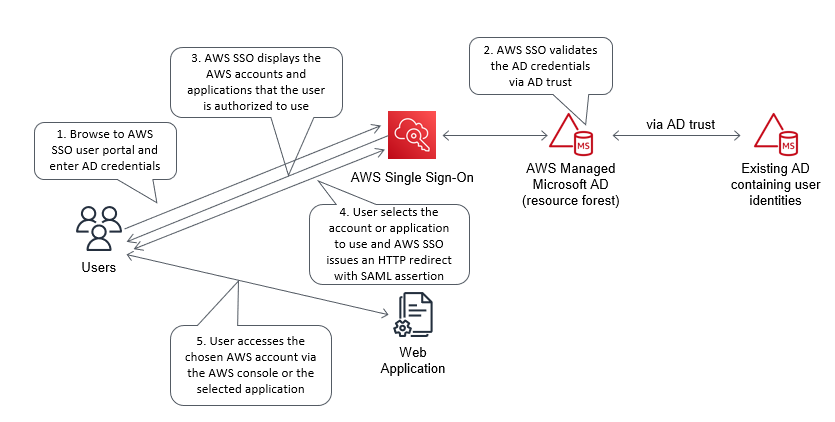
Figure 7 shows the steps that occur when you use AWS SSO to provide identity federation to a web application.
Figure 7: Example flow for identify federation that uses AWS SSO
Conclusion
This post highlights the importance of implementing a cloud authentication and authorization architecture that addresses the variety of requirements for an organization’s AWS Cloud environment. In addition to console access, this post highlights the importance of considering how you will:
Perform authentication to AWS based Windows and Linux instances
Integrate AWS services that need Windows-based authentication capabilities
Integrate authentication for internal user applications
Provide a single identity source as the source of truth for all AWS user authentication
Enable MFA for user authentication
The proposed approach provides a highly available Active Directory (AD) infrastructure, running on AWS and integrated with your existing AD, which addresses these considerations. The approach helps you to attain reduced latencies and higher levels of availability by removing dependencies on on-premises resources, other hosting locations, and external network links. This design stores the identity information that is contained within your existing AD in your chosen AWS Region and country, across multiple Availability Zones, which can also help you meet your data residency requirements.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Recently, AWS launched the ability to delegate administration of AWS Single Sign-On (AWS SSO) in your AWS Organizations organization to a member account (an account other than the management account). This post will show you a practical approach to using this new feature. For the documentation for this feature, see Delegated administration in the AWS Single Sign-On User Guide.
With AWS Organizations, your enterprise organization can manage your accounts more securely and at scale. One of the benefits of Organizations is that it integrates with many other AWS services, so you can centrally manage accounts and how the services in those accounts can be used.
AWS SSO is where you can create, or connect, your workforce identities in AWS just once, and then manage access centrally across your AWS organization. You can create user identities directly in AWS SSO, or you can bring them from your Microsoft Active Directory or a standards-based identity provider, such as Okta Universal Directory or Azure AD. With AWS SSO, you get a unified administration experience to define, customize, and assign fine-grained access.
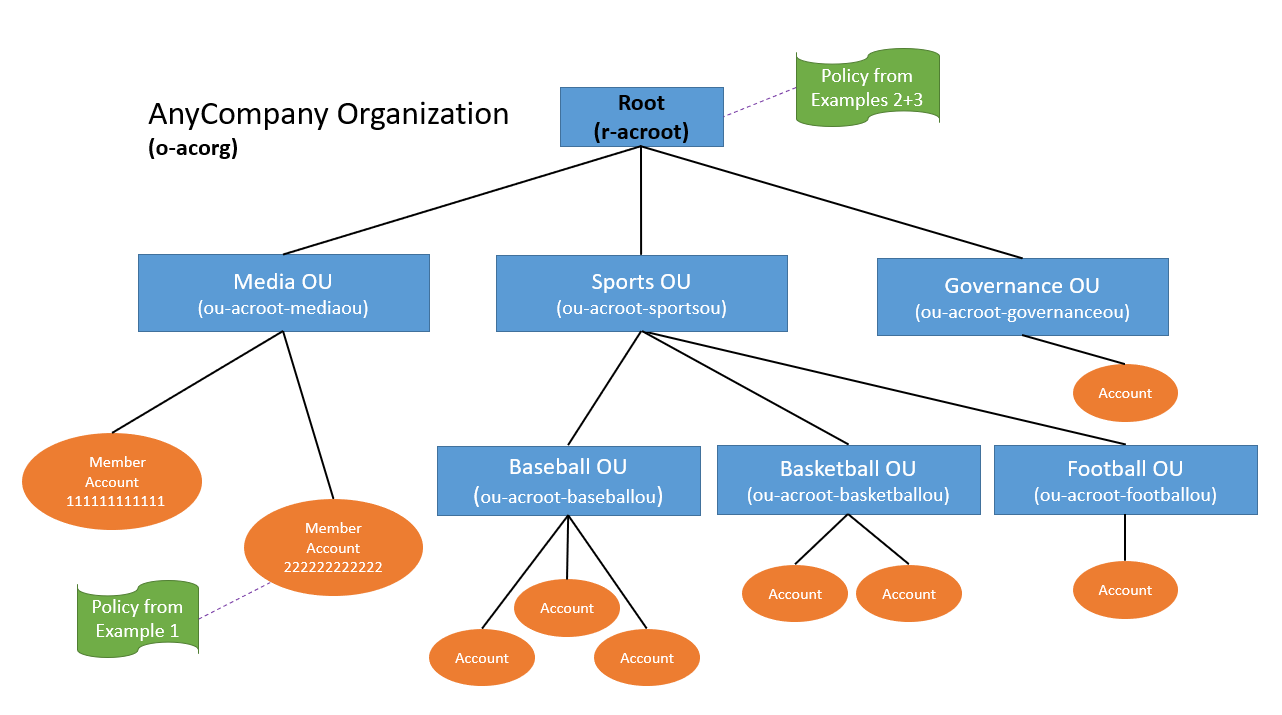
By default, the management account in an AWS organization has the power and authority to manage member accounts in the organization. Because of these additional permissions, it is important to exercise least privilege and tightly control access to the management account. AWS recommends that enterprises create one or more accounts specifically designated for security of the organization, with proper controls and access management policies in place. AWS provides a method in which many services can be administered for the organization from a member account; this is usually referred to as a delegated administrator account. These accounts can reside in a security organizational unit (OU), where administrators can enforce organizational policies. Figure 1 is an example of a recommended set of OUs in Organizations.
Figure 1: Recommended AWS Organizations OUs
Many AWS services support this delegated administrator model, including Amazon GuardDuty, AWS Security Hub, and Amazon Macie. For an up-to-date complete list, see AWS services that you can use with AWS Organizations. AWS SSO is now the most recent addition to the list of services in which you can delegate administration of your users, groups, and permissions, including third-party applications, to a member account of your organization.
How to configure a delegated administrator account
In this scenario, your enterprise AnyCompany has an organization consisting of a management account, an account for managing security, as well as a few member accounts. You have enabled AWS SSO in the organization, but you want to enable the security team to manage permissions for accounts and roles in the organization. AnyCompany doesn’t want you to give the security team access to the management account, and they also want to make sure the security team can’t delete the AWS SSO configuration or manage access to that account, so you decide to delegate the administration of AWS SSO to the security account.
Note: There are a few things to consider when making this change, which you should review before you enable delegated administration. These items are covered in the console during the process, and are described in the section Considerations when delegating AWS SSO administration in this post.
To delegate AWS SSO administration to a security account
In the AWS SSO console, navigate to the Region in which AWS SSO is enabled.
Choose Settings on the left navigation pane, and then choose the Management tab on the right side.
Under Delegated administrator, choose Register account, as shown in Figure 2.
Figure 2: The Register account button in AWS SSO
Consider the implications of designating a delegated administrator account (as described in the section Considerations when delegating AWS SSO administration). Select the account you want to be able to manage AWS SSO, and then choose Register account, as shown in Figure 3.
Figure 3: Choosing a delegated administrator account in AWS SSO
You should see a success message to indicate that the AWS SSO delegated administrator account is now setup.
To remove delegated AWS SSO administration from an account
In the AWS SSO console, navigate to the Region in which AWS SSO is enabled.
Choose Settings on the left navigation pane, and then choose the Management tab on the right side.
Under Delegated administrator, select Deregister account, as shown in Figure 4.
Figure 4: The Deregister account button in AWS SSO
Consider the implications of removing a delegated administrator account (as described in the section Considerations when delegating AWS SSO administration), then enter the account name that is currently administering AWS SSO, and choose Deregister account, as shown in Figure 5.
Figure 5: Considerations of deregistering a delegated administrator in AWS SSO
There are a few considerations you should keep in mind when you delegate AWS SSO administration. The first consideration is that the delegated administrator account will not be able to perform the following actions:
Delete the AWS SSO configuration.
Delegate (to other accounts) administration of AWS SSO.
Manage user or group access to the management account.
Manage permission sets that are provisioned (have a user or group assigned) in the organization management account.
For examples of those last two actions, consider the following scenarios:
In the first scenario, you are managing AWS SSO from the delegated administrator account. You would like to give your colleague Saanvi access to all the accounts in the organization, including the management account. This action would not be allowed, since the delegated administrator account cannot manage access to the management account. You would need to log in to the management account (with a user or role that has proper permissions) to provision that access.
In a second scenario, you would like to change the permissions Paulo has in the management account by modifying the policy attached to a ManagementAccountAdmin permission set, which Paulo currently has access to. In this scenario, you would also have to do this from inside the management account, since the delegated administrator account does not have permissions to modify the permission set, because it is provisioned to a user in the management account.
With those caveats in mind, users with proper access in the delegated administrator account will be able to control permissions and assignments for users and groups throughout the AWS organization. For more information about limiting that control, see Allow a user to administer AWS SSO for specific accounts in the AWS Single Sign-On User Guide.
Deregistering an AWS SSO delegated administrator account will not affect any permissions or assignments in AWS SSO, but it will remove the ability for users in the delegated account to manage AWS SSO from that account.
Additional considerations if you use Microsoft Active Directory
There are additional considerations for you to keep in mind if you use Microsoft Active Directory (AD) as an identity provider, specifically if you use AWS SSO configurable AD sync, and which AWS account the directory resides in. In order to use AWS SSO delegated administration when the identity source is set to Active Directory, AWS SSO configurable AD sync must be enabled for the directory. Your organization’s administrators must synchronize Active Directory users and groups you want to grant access to into an AWS SSO identity store. When you enable AWS SSO configurable AD sync, a new feature that launched in April, Active Directory administrators can choose which users and groups get synced into AWS SSO, similar to how other external identity providers work today when using the System for Cross-domain Identity Management (SCIM) v2.0 protocol. This way, AWS SSO knows about users and groups even before they are granted access to specific accounts or roles, and AWS SSO administrators don’t have to manually search for them.
Another thing to consider when delegating AWS SSO administration when using AD as an identity source is where your directory resides, that is which AWS account owns the directory. If you decide to change the AWS SSO identity source from any other source to Active Directory, or change it from Active Directory to any other source, then the directory must reside in (be owned by) the account that the change is being performed in. For example, if you are currently signed in to the management account, you can only change the identity source to or from directories that reside in (are owned by) the management account. For more information, see Manage your identity source in the AWS Single Sign-On User Guide.
Best practices for managing AWS SSO with delegated administration
AWS recommends the following best practices when using delegated administration for AWS SSO:
Maintain separate permission sets for use in the organization management account (versus the rest of the accounts). This way, permissions can be kept separate and managed from within the management account without causing confusion among the delegated administrators.
When granting access to the organization management account, grant the access to groups (and permission sets) specifically for access in that account. This helps enable the principal of least privilege for this important account, and helps ensure that AWS SSO delegated administrators are able to manage the rest of the organization as efficiently as possible (by reducing the number of users, groups, and permission sets that are off limits to them).
If you plan on using one of the AWS Directory Services for Microsoft Active Directory (AWS Managed Microsoft AD or AD Connector) as your AWS SSO identity source, locate the directory and the AWS SSO delegated administrator account in the same AWS account.
Conclusion
In this post, you learned about a helpful new feature of AWS SSO, the ability to delegate administration of your users and permissions to a member account of your organization. AWS recommends as a best practice that the management account of an AWS organization be secured by a least privilege access model, in which as few people as possible have access to the account. You can enable delegated administration for supported AWS services, including AWS SSO, as a useful tool to help your organization minimize access to the management account by moving that control into an AWS account designated specifically for security or identity services. We encourage you to consider AWS SSO delegated administration for administrating access in AWS. To learn more about the new feature, see Delegated administration in the AWS Single Sign-On User Guide.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS IAM forum or contact AWS Support.
Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
For your sensitive data on AWS, you should implement security controls, including identity and access management, infrastructure security, and data protection. Amazon Web Services (AWS) recommends that you set up multiple accounts as your workloads grow to isolate applications and data that have specific security requirements. AWS tools can help you establish a data perimeter between your multiple accounts, while blocking unintended access from outside of your organization. Data perimeters on AWS span many different features and capabilities. Based on your security requirements, you should decide which capabilities are appropriate for your organization. In this first blog post on data perimeters, I discuss which AWS Identity and Access Management (IAM) features and capabilities you can use to establish a data perimeter on AWS. Subsequent posts will provide implementation guidance and IAM policy examples for establishing your identity, resource, and network data perimeters.
A data perimeter is a set of preventive guardrails that help ensure that only your trusted identities are accessing trusted resources from expected networks. These terms are defined as follows:
Trusted identities – Principals (IAM roles or users) within your AWS accounts, or AWS services that are acting on your behalf
Trusted resources – Resources that are owned by your AWS accounts, or by AWS services that are acting on your behalf
Expected networks – Your on-premises data centers and virtual private clouds (VPCs), or networks of AWS services that are acting on your behalf
Data perimeter guardrails
You typically implement data perimeter guardrails as coarse-grained controls that apply across a broad set of AWS accounts and resources. When you implement a data perimeter, consider the following six primary control objectives.
Data perimeter
Control objective
Identity
Only trusted identities can access my resources.
Only trusted identities are allowed from my network.
Resource
My identities can access only trusted resources.
Only trusted resources can be accessed from my network.
Network
My identities can access resources only from expected networks.
My resources can only be accessed from expected networks.
Note that the controls in the preceding table are coarse in nature and are meant to serve as always-on boundaries. You can think of data perimeters as creating a firm boundary around your data to prevent unintended access patterns. Although data perimeters can prevent broad unintended access, you still need to make fine-grained access control decisions. Establishing a data perimeter does not diminish the need to continuously fine-tune permissions by using tools such as IAM Access Analyzer as part of your journey to least privilege.
To implement the preceding control objectives on AWS, use three primary capabilities:
Service control policies (SCPs) – AWS Organizations policies that you can use to establish the maximum available permissions for your principals (IAM roles or users) within your organization. SCPs help you ensure that your accounts stay within your organization’s access control guidelines. In the context of data perimeters, you use SCPs so that your identities can access only trusted resources from expected networks.
VPC endpoint policies – Policies that you attach to VPC endpoints to control which principals, actions, and resources can be accessed by using a VPC endpoint. In the context of data perimeters, use VPC endpoint policies to specify that your network can be used only by trusted identities to access only trusted resources. For a list of services that support VPC endpoints and VPC endpoint policies, see AWS services that integrate with AWS PrivateLink.
Let’s expand the previous table to include the corresponding policies you would use to implement the controls for each of the control objectives.
Data perimeter
Control objective
Implemented by using
Identity
Only trusted identities can access my resources.
Resource-based policies
Only trusted identities are allowed from my network.
VPC endpoint policies
Resource
My identities can access only trusted resources.
SCPs
Only trusted resources can be accessed from my network.
VPC endpoint policies
Network
My identities can access resources only from expected networks.
SCPs
My resources can only be accessed from expected networks.
Resource-based policies
As you can see in the preceding table, the correct policy for each control objective depends on which resource you are trying to secure. Resource-based policies, which are applied to resources such as Amazon S3 buckets, can be used to filter access based on the calling principal and the network from which they are making a call. VPC endpoint policies are used to inspect the principal that is making the API call and the resource they are trying to access. And SCPs are used to restrict your identities from accessing resources outside your control or from outside your network. Note that SCPs apply only to your principals within your AWS organization, whereas resource policies can be used to limit access to all principals.
The last components are the specific IAM controls or condition keys that enforce the control objective. For effective data perimeter controls, use the following primary IAM condition keys, including the new resource owner condition keys:
aws:PrincipalOrgID – Use this condition key to restrict access to trusted identities, your principals (roles or users) that belong to your organization. In the context of a data perimeter, you will use this condition key with your resource-based policies and VPC endpoint policies.
aws:ResourceOrgID – Use this condition key to restrict access to resources that belong to your AWS organization. To establish a data perimeter, you will use this condition key within SCPs and VPC endpoint policies.
aws:SourceIp, aws:SourceVpc, aws:SourceVpce – Use these condition keys to restrict access to expected network locations, such as your corporate network or your VPCs. In the context of a data perimeter, you will use these keys within identity and resource-based policies.
We can now complete the table that we’ve been developing throughout this post.
Data perimeter
Control objective
Implemented by using
Primary IAM capability
Identity
Only trusted identities can access my resources.
Resource-based policies
aws:PrincipalOrgID aws:PrincipalIsAWSService
Only trusted identities are allowed from my network.
VPC endpoint policies
aws:PrincipalOrgID
Resource
My identities can access only trusted resources.
SCPs
aws:ResourceOrgID
Only trusted resources can be accessed from my network.
VPC endpoint policies
aws:ResourceOrgID
Network
My identities can access resources only from expected networks.
For the identity data perimeter, the primary condition key is aws:PrincipalOrgID, which you can use in resource-based policies and VPC endpoint policies so that only your identities are allowed access. Use aws:PrincipalIsAWSService to allow AWS services to access your resources by using their own identities—for example, AWS CloudTrail can use this access to write data to your bucket.
For the resource data perimeter, the primary condition key is aws:ResourceOrgID, which you can use in an SCP policy or VPC endpoint policy to allow your identities and network to access only the resources that belong to your AWS organization.
In this blog post, you learned the foundational elements that are needed to implement an identity, resource, and network data perimeter on AWS, including the primary IAM capabilities that are used to implement each of the control objectives. Stay tuned to the follow-up posts in this series, which will provide prescriptive guidance on establishing your identity, resource, and network data perimeters.
Following are additional resources that will help you further explore the data perimeter topic, including a whitepaper and a hands-on-workshop. We have also curated several blog posts related to the key IAM capabilities discussed in this post.
If you have any questions, comments, or concerns, contact AWS Support or start a new thread on the IAM forum. If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security news? Follow us on Twitter.
Many organizations restrict permissions to create and manage AWS Identity and Access Management (IAM) resources to a group of privileged users or a central team. This post explains how you can safely grant these permissions to builders – the people who are developing, testing, launching, and managing cloud infrastructure – to speed up your development, increase your agility, and improve your application security. In addition, you will use an example application stack to see how IAM permissions boundaries can help establish a secure, yet agile work environment for builders.
An example application stack
Defining and creating IAM resources within the application stack allows your builders to craft policies and roles that grant least privilege to application resources. When builders are entitled to create IAM resources, it is straightforward for them to scope policies by referencing the application resources directly in the IAM policies in the same template.
To illustrate this point you will build a simple “hello world” serverless application. The application includes an AWS Step Functions state machine that, once executed, will invoke an AWS Lambda function. You will use this example application along with some IAM policies and IAM roles to illustrate how you can use permissions boundaries to safely grant IAM privileges to builders.
In this example AWS CloudFormation template, the Resource element in MyStateMachineExecutionRole, which is specified as the role for MyStateMachine, includes a reference to the Amazon Resource Name (ARN) of MyLambdaFunction. This is a great example of the principle of least privilege as MyStateMachine will only have permissions to invoke MyLambdaFunction. Making this association is straightforward because the IAM, Step Functions, and Lambda resources are defined together in the same template.
In an organization that uses a centralized approach to IAM management, a builder would not be able to deploy this example application because the roles the builders are granted prohibit IAM actions related to creating and managing roles and policies. This creates three key challenges for the organization:
Builders often rely on a security or cloud team to create IAM resources. This approach adds an additional burden to that team which slows down development while builders wait for the roles and policies to be created, and encourages the team to grant overly-broad permissions so that they don’t have to be involved in the precise details of changes on a daily basis.
IAM resources must be created before the rest of the stack, which makes it much more difficult to create least-privilege policies and roles.
The code for IAM and application infrastructure is maintained separately, which requires extra coordination when creating and updating workloads.
Removing these challenges can simplify your cloud development, lower the amount of overhead and coordination required across your organization, and improve your security posture. Further, reducing the burden on your security team can free up time for them to focus on enforcing additional data perimeters and implementing best practices from the security pillar of the AWS Well-Architected Framework.
Use permissions boundaries on application roles created by builders
So how can your organization shift to a decentralized approach to IAM management and allow builders to safely create application IAM policies and roles, as well as prevent builders from being able to escalate their own privileges? This is a scenario where permissions boundaries should be used.
Permissions boundaries allow an IAM policy to be attached to an IAM role to enforce limits on the permissions that role can be granted. The permissions boundary itself does not grant any permissions – it’s just a guardrail that defines the maximum entitlements. You can create a builder policy that requires a specified permissions boundary be attached to any application roles that a builder creates, effectively setting the maximum permissions on any role that a builder can generate. The permissions for any application roles created will be the intersection of the application policies and the permissions boundary associated with the application role. Said another way, a permission granted in the application policy must also be granted in the permissions boundary, or else it will be implicitly denied according to the policy evaluation logic.
The set of permissions required for builder roles (assumed by actual people or CI/CD pipelines) to deploy infrastructure and develop applications are different than those required for application roles (assumed by workloads/applications) to execute within applications and workflows. If you think of permissions in terms of control plane actions involved in creating, deleting, and modifying resources, versus data plane actions needed to execute the daily business of those resources, builder and application roles typically operate more on the control plane and data plane, respectively. While permissions policies attached to application roles should be tightly scoped to include only those actions needed to perform a specific task, policies for permissions boundaries should be highly reusable and include a broad set of permissions across a suite of services that a variety of applications might need. In addition, it is a best practice to not share roles between humans and services. To summarize, policies for builder and application roles should be designed with the following criteria in mind:
Policy
Role
Permissions
Scope
Reusability
User
builder
builder
control plane
broad
high
human
application
application
data plane
specific
low
service
application-boundary
application
data plane
broad
high
application role
Following the steps in this section, you will create:
A builder policy that grants builders permissions for services needed to deploy and manage applications, and to create and manage IAM policies and roles for those applications.
An application-boundary policy that defines the extent of the permissions any application role created by a builder can have.
A builder role with the builder policy attached as the permissions policy, the application-boundary policy attached as a permissions boundary, and a trust policy that allows anyone in the account to assume the builder role.
Create the builder IAM resources
In this first procedure, you will use CloudFormation to create the builder and application-boundary IAM policies, and the builder IAM role.
To launch the builder IAM stack
Open a Linux terminal with the AWS Command Line Interface (CLI) installed and AWS credentials configured for a user or role that has permissions to create IAM resources.
Launch the builder IAM stack by using the following command:
The builder policy you created uses paths to organize IAM policies and roles into isolated “spaces” that can be specified as resource constraints. It also requires roles to have a permissions boundary attached. This approach helps manage role delegation and prevents builders from escalating their privileges or modifying roles that may be used by other teams.
Note that paths can only be added to IAM resources using the AWS CLI or APIs – not via the console. If this is an issue, another option is to specify that policies and roles start with a specific phrase, for example “application-roles-*”. Just be sure to use different phrases for the builder, application, and permissions boundaries resources to maintain isolation and prevent builders from being able to escalate their privileges.
The builder policy also includes some basic control plane permissions, while the application-boundary policy you created includes permissions used across a suite of services that a typical serverless application might need. However, both policies are only meant to demonstrate the concepts in this blog post. In practice, you will need to create policies that more accurately reflect the permissions needed by builder and application roles in your organization. See the example-permissions-boundaries repository on the AWS Samples GitHub site for more ideas.
Use the builder role to launch an application stack
In this section you will assume the builder role and verify that you can launch the application stack, including the application roles, but only if the required permissions boundary and path are specified.
To test launching a stack that creates application roles
Assume the builder role by using the following set of commands (copy and paste into the terminal as a single block). This step uses the jq program, which is available in most operating system package repositories.
You will use this role for all of the following procedures up until the “Clean up” section. If, during the course of this exercise, you get an error that “The security token included in the request is expired”, create a new terminal and repeat this step to get a fresh set of credentials.
The trust policy for the builder role allows any principal in the account to assume it. You can use a combination of the Principal and Condition attributes to further reduce its scope. Normally builder roles are assumed directly via federation or AWS SSO.
Check that the you have now assumed the builder role by using the following command:
aws sts get-caller-identity
Launch the example application stack by using the following command:
If things are set up correctly, the stack will fail. To confirm, check the StackStatus by using the following command – it should show ROLLBACK_IN_PROGRESS or ROLLBACK_COMPLETE.
The stack failed to create because the builder role you assumed does not have permissions to create the two application roles without specifying the /application_roles/ path and attaching a permissions boundary with /permissions_boundaries/ in the path. To see the details, use the following command:
If the original stack did not create successfully, you will not be able to update it, so you will need to delete it instead by using the following command:
Start an execution of the state machine and verify the application is working by using the following commands. Run them one at a time to allow the execution to finish.
If the output is “\”Hello Builder!\””, then the application is working.
Test that a builder can’t escalate their privileges
In this section, you will test scenarios where a builder attempts, intentionally or not, to escalate their privileges by first modifying the policies attached to the builder role and then extending the permissions of an application role beyond the permissions boundary.
To test updating a builder policy attached to the builder role
Create an environment variable for your AWS account number, which will be used in several of the steps below, using the following command:
You should not get an error in this step because you are creating a new policy that complies with the resource constraint for the statement that includes the iam:CreatePolicy permission in the builder policy. But, it’s just a policy for now – it can’t have any effect unless attached to a role.
Now try to attach this new policy to the builder role by using the following command:
aws iam attach-role-policy \
--role-name builder \
--policy-arn arn:aws:iam::$AWS_ACCOUNT:policy/application_policies/sneaky-policy
You should get an error because you’re attempting to attach a policy to a role that’s not in the /application-roles/ space, in this case the builder role.
To test modifying an application role with actions outside the permissions boundary
In this procedure, you will attempt to escalate the privileges of the MyLambdaFunctionExecutionRole by adding an action (s3:CreateBucket) that is outside of the permissions boundary attached to the role and then attempting to execute that action when MyLambdaFunction is invoked.
Update the builder-application stack by using the following command:
Start an execution of the state machine and verify the result by using the following commands. Run them one at a time to allow the execution to finish.
The status should be FAILED. Remember – the effective permissions for any application roles will be the intersection of the attached permissions policies and the permissions boundary. Thus, this execution failed because even though you were able to modify the inline policy of the Lambda function to add s3:CreateBucket, since that action is not allowed in the application-boundary policy attached to the Lambda as a permissions boundary, the request to create an S3 bucket was denied.
Get the name of the latest log stream by using the following commands:
To verify the actual error was due to a lack of permissions, get the event message by using the following command, replacing <value> with the value of the log stream copied in the step above. If using a bash terminal, you will need to escape any dollar signs in <value> with a backslash character:
The error should read [ERROR] ClientError: An error occurred (AccessDenied) when calling the CreateBucket operation: Access Denied, which confirms that the permissions boundary prevented you from escalating your privileges as a builder via an application role.
You have now verified that you can safely allow builders to create IAM policies and roles!
Clean up
After you have finished testing, clean up the resources created in this example. Because the builder role does not have permissions to delete builder policies and roles, you will need to assume a different role that can manage IAM resources to complete step 3 below. If you create a new terminal session, make sure the AWS_ACCOUNT environment variable is set.
To clean up
Delete the builder-application stack by using the following command:
Permissions boundaries are applied to individual IAM users or roles within an account. If your organization has multiple accounts, you must create and maintain these boundaries in each account for each individual user or role. But what if you’d like to apply a subset of these rules or others across some or all of your accounts? In this case, you could use service control policies (SCPs), which are a feature of AWS Organizations, to provide central control over the maximum available permissions for multiple accounts in your organization. By organizing accounts into organizational units (OUs), which are groups of accounts that serve an application or service, you can apply service control policies (SCPs) to create targeted governance boundaries for your OUs. To learn more about creating SCPs, see Get more out of service control policies in a multi-account environment in the AWS Security Blog.
Additional tools
Creating and managing tightly scoped policies and roles is an ongoing process that requires a lot of thought and attention to detail. AWS IAM enables fine-grained access control to AWS services, and permissions boundaries are an advanced feature. There is no substitute for actual testing like you performed in the “Test that a builder can’t escalate their privileges” section above, however you can also use the IAM Policy Simulator as a tool to test policies and determine whether or not specific actions are allowed for a given user, group, or role. Additional tools you can use to create, audit, and update IAM policies include:
Access Advisor – to review when services and actions were last accessed.
Access Analyzer – to help identify resources in your organization and accounts that are shared with an external identity, validate IAM policies against policy grammar and best practices, and generate IAM policies based on access activity in your AWS CloudTrail logs.
AWS Cloud Development Kit (CDK) – has built-in convenience methods to help you follow best practices, including the ability to generate least-privilege policies for cloud applications with a single line of code.
Open Source tools like cfn-nag and cdk-nag – to inspect CloudFormation templates and CDK applications for patterns that may indicate insecure infrastructure, for example IAM policies that are too permissive.
Conclusion
In this post, you learned how to put policies and guardrails in place that will allow your organization to grant IAM permissions to builders. These changes will enable your builders to develop and deploy cloud infrastructure and applications more rapidly, and will help strengthen your organization’s security culture by extending the responsibility to a broader group. To learn more about creating, testing, and refining IAM policies and permissions boundaries, see Creating IAM policies, Testing IAM policies, and Refining permissions using access information in the IAM User Guide, and IAM policy types: How and when to use them in the AWS Security Blog.
If you run container workloads that use Amazon Elastic Kubernetes Service (Amazon EKS), Amazon GuardDuty now has added support that will help you better protect these workloads from potential threats. Amazon GuardDuty EKS Protection can help detect threats related to user and application activity that is captured in Kubernetes audit logs. Newly-added Kubernetes threat detections include Amazon EKS clusters that are accessed by known malicious actors or from Tor nodes, API operations performed by anonymous users that might indicate a misconfiguration, and misconfigurations that can result in unauthorized access to Amazon EKS clusters. By using machine learning (ML) models, GuardDuty can identify patterns consistent with privilege-escalation techniques, such as a suspicious launch of a container with root-level access to the underlying Amazon Elastic Compute Cloud (Amazon EC2) host. In this post, we give you an overview of the new GuardDuty EKS Protection feature; show you examples of new finding details; and help you understand, operationalize, and respond to these new findings.
Amazon GuardDuty is an automated threat detection service that continuously monitors for suspicious activity and potentially unauthorized behavior to help protect your AWS accounts, Amazon EC2 workloads, data stored in Amazon Simple Storage Service (S3), and now Amazon EKS workloads.
If you are already a GuardDuty customer, you can enable GuardDuty EKS Protection and efficiently navigate the console to begin to use this feature. Your delegated administrator accounts can enable this for existing member accounts and determine if new AWS accounts in an organization will be automatically enrolled. If you are new to GuardDuty, the EKS Protection feature is included as part of the service’s 30-day trial period. As part of the 30-day trial period, you can take full advantage of this new feature and gain insight into your Amazon EKS workloads.
Overview of GuardDuty EKS Protection
GuardDuty EKS Protection enables GuardDuty to detect suspicious activities and potential compromises of your EKS clusters by analyzing Kubernetes audit logs. Kubernetes audit logs provide a security relevant, chronological set of records documenting the sequence of events from individual users, administrators, or system components that have affected your cluster. Audit logs can help answer questions such as: What happened? When did it happen? Who initiated it? GuardDuty EKS Protection analyzes Kubernetes audit logs from your Amazon EKS clusters, both new and existing, without the need to configure EKS control plane logging in your environment. GuardDuty collects these Kubernetes audit logs in addition to AWS CloudTrail, Amazon Virtual Private Cloud (Amazon VPC) flow logs, DNS queries, and Amazon S3 data events. GuardDuty EKS Protection performs analysis and looks for suspicious activity without the need for agents or adding resource constraints to your environment.
To detect threats using Kubernetes audit logs, GuardDuty uses a combination of machine learning, anomaly detection, and integrated threat intelligence to identify and prioritize potential threats. These findings primarily align to five root causes including compromised container images, configuration issues, Kubernetes user compromise, pod compromise, and node compromise. An example of a configuration issue is granting unnecessary privileges to the anonymous user by misconfiguring role-based access control (RBAC), which may inadvertently allow anonymous and unauthenticated calls to the Kubernetes API. A Kubernetes user compromise example could be a bad actor using stolen credentials to deploy containers with insecure settings, to use for a variety of activities from command and control to crypto-mining.
After a threat is detected, GuardDuty generates a security finding that includes container details such as the pod ID, container image ID, and tags associated with the Amazon EKS cluster. These finding details assist you with understanding the root cause which you can use to identify basic steps to remediate findings specific to EKS clusters. For example, your response to a finding or group of findings associated with a compromised Kubernetes user might begin with revoking access. For more information, see Remediating Kubernetes security issues discovered by GuardDuty in the Amazon GuardDuty User Guide.
Understanding new GuardDuty EKS Protection findings
As adversaries continue to become more sophisticated, it becomes even more important for you to align to a common framework to understand the tactics, techniques, and procedures (TTPs) behind an individual event. GuardDuty aligns findings using the MITRE ATT&CK framework, which is a globally-accessible knowledge base of adversary tactics and techniques based on real-world observations. GuardDuty findings have a specific finding format that helps you understand details of each finding. If you examine the ThreatPurpose portion in the GuardDuty EKS Protection finding types, you see there are finding types associated with various MITRE ATT&CK tactics, including CredentialAccess, DefenseEvasion, Discovery, Impact, Persistence, and PrivilegeEscalation. This can help you identify and understand the type of activity associated with a finding.
For example, look at two different finding types that seem similar: Impact:Kubernetes/SuccessfulAnonymousAccess and Discovery:Kubernetes/SuccessfulAnonymousAccess. You can see the difference is the ThreatPurpose at the beginning. They are both involved with successful anonymous access, and the difference is the intent of the activity associated with each finding. GuardDuty has determined based on the API or request URI invoked, that in this example, the activity seen on one finding aligns with the Impact tactic whereas the other finding aligns with the Discovery tactic
With GuardDuty EKS Protection, you now have an additional mechanism to gain insight into your EKS clusters across your accounts to look for suspicious activity. You can be alerted to Kubernetes-specific suspicious activity including: allowing administrator access to the default service account, exposing a Kubernetes dashboard, and launching a container with sensitive host paths. With this new feature, GuardDuty is also able to extend support for finding types that you might already be familiar with that also apply to Amazon EKS workloads. These finding types include calls to a Kubernetes cluster API from a Tor node, or calls to a Kubernetes cluster from a known malicious IP address, which can indicate that there are interactions with your Kubernetes clusters from sources that are commonly associated with malicious actors.
Responding to GuardDuty EKS Protection findings
This section gives an overview of three new GuardDuty EKS Protection findings, how to prevent them, and how to investigate and respond if they happen in your environment. The patterns shown can also act as a guide for how to prevent, investigate, and respond to other GuardDuty EKS Protection findings.
Overview: This finding (as shown in Figure 1) informs you that an API operation was successfully invoked by the system:anonymous user. API calls made by system:anonymous are unauthenticated. The observed API is commonly associated with the discovery stage of an attack when an adversary is gathering information on your Kubernetes cluster. This activity indicates that anonymous or unauthenticated access is permitted on the API action reported in the finding, and may be permitted on other actions. These API calls are possible because of a misconfiguration of the system:anonymous user or system:unauthenticated group.
Preventative measures: AWS recommends that you disable unnecessary anonymous authentication. For instructions, see Review and revoke unnecessary anonymous access in the Amazon EKS Best Practices Guides. It is important to note that Kubernetes versions older than 1.14 granted system:discovery and system:basic-user roles to system:anonymous user by default, and these permissions remain in place after updating unless you explicitly change them.
How to remediate: To respond to this finding, it is important to first identify the details of the activity, for example what cluster is involved? Who is the owner of this cluster? This information will assist you with the remediation steps that follow, to review and revoke unnecessary permissions, and also help you determine a root cause.
Figure 1: GuardDuty Console showing Discovery:Kubernetes/SuccessfulAnonymousAccess finding type
Remediation step 1: Examine permissions
The first step is to examine the permissions that have been granted to the system:anonymous user, and determine what permissions are needed. To accomplish this, you need to first understand what permissions the system:anonymous user has. You can use an rbac-lookup tool to list the Kubernetes roles and cluster roles bound to users, service accounts, and groups. An alternative method can be found at this GitHub page.
Next, you disassociate the system:unauthenticated group from system:discovery and system:basic-user ClusterRoles, which you do by editing the ClusterRoleBinding. Make sure to not remove system:unauthenticated from the system:public-info-viewer cluster role binding, because that will prevent the Network Load Balancer from performing health checks against the API server. For more information, see Network Load Balancer in the AWS Load Balancer Controller Guide and Identity and Access Management in Amazon EKS Best Practices Guide.
To disassociate the appropriate groups
Run the command kubectl edit clusterrolebindings system:discovery. This command will open the current definition of system:discovery ClusterRoleBinding in your editor as shown in the sample .yaml configuration file:
# Please edit the object below. Lines beginning with a '#' will be ignored,
# and an empty file will abort the edit. If an error occurs while saving this # file will be reopened with the relevant failures.
#
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRoleBinding
metadata:
  annotations:
    rbac.authorization.kubernetes.io/autoupdate: "true"
  creationTimestamp: "2021-06-17T20:50:49Z"
  labels:
    kubernetes.io/bootstrapping: rbac-defaults
  name: system:discovery
  resourceVersion: "24502985"
  selfLink: /apis/rbac.authorization.k8s.io/v1/clusterrolebindings/system%3Adiscovery
  uid: b7936268-5043-431a-a0e1-171a423abeb6
roleRef:
  apiGroup: rbac.authorization.k8s.io
  kind: ClusterRole
  name: system:discovery
subjects:
- apiGroup: rbac.authorization.k8s.io
  kind: Group
  name: system:authenticated
- apiGroup: rbac.authorization.k8s.io
  kind: Group
  name: system:unauthenticated
Delete the entry for system:unauthenticated group, which is highlighted in bold in the subjects section.
Repeat the same steps for system:basic-user ClusterRoleBinding.
If there is no reason that the system:anonymous user should be used in your environment, AWS recommends that you set up automatic response and remediation steps 1-3. For more information about the system:anonymous user, see Identity and Access Management in Amazon EKS Best Practices Guide.
Overview: This finding (as shown in Figure 2) informs you that a privileged container was launched on your Kubernetes cluster using an image that has never before been used to launch privileged containers in your cluster. A privileged container has root level access on the host. Adversaries commonly launch privileged containers to perform privilege escalation to gain access and compromise the underlying host.
Preventative measures: Create and enforce policy-as-code (PAC) or Pod Security Standards (PSS) that require that pods be created as non-privileged. For more information, see Pod Security in the in Amazon EKS Best Practices Guide.
How to remediate: To respond to this finding, it is important to first identify the details of the activity and begin to answer questions that will help determine what happened. For example, what pod or workload was launched? Who was the user that launched this pod or workload? What cluster is involved?
Figure 2: GuardDuty Console showing PrivilegeEscalation:Kubernetes/PrivilegedContainer finding type
If this privileged container launch is unexpected, the credentials of the user identity used to launch the container may be compromised. You should then focus on remediating and reviewing access to your cluster, and remediating the user. To do this, follow the procedure in the Remediating a compromised Kubernetes user section of this post. Next, you should identify compromised pods using the procedure in the Identifying and remediating compromised pods section of this post.
If you know what specific circumstances a privileged container can be deployed in your environment, for example only in a specific namespace, it is likely you can automatically remediate any GuardDuty EKS Protection finding associated with a privileged container in any other namespace. For more information about automated response activities, see Incident response and forensics in the Amazon EKS Best Practices Guide.
Overview: This finding (as shown in Figure 3) informs you that a container was launched with a configuration that included a sensitive host path with write access in the volumeMounts section. This makes the sensitive host path accessible and writable from inside the container. This technique is commonly used by adversaries to gain access to the host’s filesystem.
Preventative Measures: Create and enforce policy-as-code (PAC) or Pod Security Standards (PSS) that use the allowedHostPaths control to only allow required host paths for use in volumes and preferably with read-only access. For more information, see Pod Security in the Amazon EKS Best Practices Guide.
How to remediate: To respond to this finding, it is important to first identify the details of the activity and begin to answer questions that will help determine what happened. For example, what pod or workload was launched? Who was the user that launched this pod or workload? What cluster is involved?
Figure 3: GuardDuty Console showing Persistence:Kubernetes/ContainerWithSensitiveMount finding type
If the container launched is unexpected, the credentials of the user identity used to launch the container may be compromised. You should then focus on remediating and reviewing access to your cluster and remediating the user. To do this, follow the procedure in the next section, Remediating a compromised Kubernetes user.
If you can determine what containers should and should not be launched with writable hostPath mounts, then you can create automatic response and remediation for this use case. For example, you might want to revoke temporary security credentials assigned to the pod or worker node. For more information about revoking temporary security credentials and other response and remediation actions, see Incident response and forensics in the Amazon EKS Best Practices Guide.
Remediating a compromised Kubernetes user
If the compromised user has privileges to read secrets of one or more namespaces, rotate all of the affected secrets. For more information about the different types of secrets, see Secrets in the Kubernetes documentation. If the user has write privileges, AWS recommends auditing all changes made by the user in question. You can accomplish this by querying audit logs, if you have enabled EKS control plane logging on your EKS cluster. If you do not currently have logging enabled, follow the instructions for Enabling and disabling control plane logs in the Amazon EKS User Guide. Amazon EKS stores these control plane logs in Amazon CloudWatch Logs in your account. You can use CloudWatch Logs Insights to list all the mutating changes that the compromised user has made.
Remediation step 1: Identify the user
All actions performed on a Kubernetes cluster has an associated identity. GuardDuty EKS Protection findings report details of the Kubernetes user identity that the malicious actor may have compromised. You can find details of the user identity in the GuardDuty console under the Kubernetes user details section in the finding details, or in the finding JSON under the resources.eksClusterDetails.kubernetesDetails.kubernetesUserDetails section. These user details include username, UID, and groups that the user belongs to.
Remediation step 2: Identify changes
Identify the changes made by the attacker associated with the compromised user identity by using the code example below to query CloudWatch Logs Insights, replacing the placeholders with your values.
fields @timestamp, @message
| filter user.username == <username>
| filter verb == "create" or verb == "update" or verb == "patch"
| filter responseStatus.code >= 200 and responseStatus.code <= 300
| filter @timestamp >= <approximate start time of the attack in epoch milliseconds>
An EKS cluster can have multiple types of user identities, for example the kubernetes-admin user, aws-auth ConfigMap defined user, and so on. You will need to take actions appropriate for the user type to properly revoke its access. For more information, see Remediating compromised Kubernetes users in the Amazon GuardDuty User Guide.
(Optional) If the compromised user identity had extensive privileges and you determine that the attacker made extensive changes to the cluster, you should consider isolating the pod, followed by creating a new clean cluster and redeploying your applications to the new cluster. For instructions to isolate and redeploy EKS pods, see Isolate the Pod by creating a Network Policy that denies all ingress and egress traffic to the pod in the Amazon EKS Best Practices Guide.
Identifying and remediating compromised pods
If a GuardDuty EKS Protection finding is caused by activity related to a specific pod, the value of the finding JSON resource.kubernetesDetails.kubernetesWorkloadDetails.type field is pod. The finding includes the name of the pod and namespace in the resource.kubernetesDetails.kubernetesWorkloadDetails.name and resource.kubernetesDetails.kubernetesWorkloadDetails.namespace fields, which uniquely identify the pod.
In other cases, such as when a service account or a Kubernetes workload name is in the resource.kubernetesDetails.kubernetesUserDetails, you can follow the instructions in the Sample incident response plan to identify compromised pods using different pieces of information available in the GuardDuty EKS Protection findings.
In this post, you learned the details of the new Amazon GuardDuty EKS Protection feature, and Kubernetes audit logs, and you saw examples for how to understand, operationalize, and respond to these new findings. You can enable this feature through the GuardDuty Console or APIs to start monitoring your Amazon EKS clusters today. If you have created Amazon EventBridge Rules to send findings from GuardDuty to a target, then ensure that your rules are configured to deliver these newly added findings.
AWS is committed to continually improving GuardDuty, to make it more efficient for you to operate securely in AWS. At AWS, customer feedback drives change, so we encourage you to continue providing feedback. If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post or contact AWS Support.
Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
A new International Data Corporation (IDC) whitepaper sponsored by AWS, Trusted Cloud: Overcoming the Tension Between Data Sovereignty and Accelerated Digital Transformation, examines the importance of the cloud in building the future of digital EU organizations. IDC predicts that 70% of CEOs of large European organizations will be incentivized to generate at least 40% of their revenues from digital by 2025, which means they have to accelerate their digital transformation. In a 2022 IDC survey of CEOs across Europe, 46% of European CEOs will accelerate the shift to cloud as their most strategic IT initiative in 2022.
In the whitepaper, IDC offers perspectives on how operational effectiveness, digital investment, and ultimately business growth need to be balanced with data sovereignty requirements. IDC defines data sovereignty as “a subset of digital sovereignty. It is the concept of data being subject to the laws and governance structures within the country it is collected or pertains to.”
IDC provides a perspective on some of the current discourse on cloud data sovereignty, including extraterritorial reach of foreign intelligence under national security laws, and the level of protection for individuals’ privacy in-country or with cross-border data transfer. The Schrems II decision and its implications with respect to personal data transfers between the EU and US has left many organizations grappling with how to comply with their legal requirements when transferring data outside the EU.
IDC provides the following background on controls in the cloud:
Cloud providers do not have unrestricted access to customer data in the cloud. Organizations retain all ownership and control of their data. Through credential and permission settings, the customer is the controller of who has access to their data.
Cloud providers use a rigorous set of organizational and technical controls based on least privilege to protect data from unauthorized access and inappropriate use.
Most cloud service operations, including maintenance and trouble-shooting, are fully automated. Should human access to customer data be required, it is temporary and limited to what is necessary to provide the contracted service to the customer. All access should be strictly logged, monitored, and audited to verify that activity is valid and compliant.
Technical controls such as encryption and key management assume greater importance. Encryption is considered fundamental to data protection best practices and highly recommended by regulators. Encrypted data processed in memory within hardware-based trusted execution environment (TEEs), also known as enclaves, can alleviate these regulatory concerns by rendering sensitive information invisible to host operating systems and cloud providers. The AWS Nitro System, the underlying platform that runs Amazon EC2 instances, is an industry example that provides such protection capability.
Independent accreditation against official standards are a recognized basis for assessing adherence to privacy and security practices. Approved by the European Data Protection Board, the EU Cloud Code of Conduct and CISPE’s Code of Conduct for Cloud Infrastructure Service Providers provide an accountability framework to help demonstrate compliance with processor obligations under GDPR Article 28. Whilst not required for GDPR compliance, CISPE requires accredited cloud providers to offer customers the option to retain all personal data in their customer content in the European Economic Area (EEA).
Greater data control and security is often cited as a driver to hosting data in-country. However, IDC notes that the physical location of the data has no bearing on mitigating data risk to cyber threats. Data residency can run counter to an organization’s objectives for security and resilience. More and more European organizations now are trusting the cloud for their security needs, as many organizations simply do not have the resource and expertise to provide the same security benefits as large cloud providers can.
AWS Identity and Access Management (IAM) recently launched new condition keys to make it simpler to control access to your resources along your Amazon Web Services (AWS) organizational boundaries. AWS recommends that you set up multiple accounts as your workloads grow, and you can use multiple AWS accounts to isolate workloads or applications that have specific security requirements. By using the new conditions, aws:ResourceOrgID, aws:ResourceOrgPaths, and aws:ResourceAccount, you can define access controls based on an AWS resource’s organization, organizational unit (OU), or account. These conditions make it simpler to require that your principals (users and roles) can only access resources inside a specific boundary within your organization. You can combine the new conditions with other IAM capabilities to restrict access to and from AWS accounts that are not part of your organization.
This post will help you get started using the new condition keys. We’ll show the details of the new condition keys and walk through a detailed example based on the following scenario. We’ll also provide references and links to help you learn more about how to establish access control perimeters around your AWS accounts.
Consider a common scenario where you would like to prevent principals in your AWS organization from adding objects to Amazon Simple Storage Service (Amazon S3) buckets that don’t belong to your organization. To accomplish this, you can configure an IAM policy to deny access to S3 actions unless aws:ResourceOrgID matches your unique AWS organization ID. Because the policy references your entire organization, rather than individual S3 resources, you have a convenient way to maintain this security posture across any number of resources you control. The new conditions give you the tools to create a security baseline for your IAM principals and help you prevent unintended access to resources in accounts that you don’t control. You can attach this policy to an IAM principal to apply this rule to a single user or role, or use service control policies (SCPs) in AWS Organizations to apply the rule broadly across your AWS accounts. IAM principals that are subject to this policy will only be able to perform S3 actions on buckets and objects within your organization, regardless of their other permissions granted through IAM policies or S3 bucket policies.
New condition key details
You can use the aws:ResourceOrgID, aws:ResourceOrgPaths, and aws:ResourceAccount condition keys in IAM policies to place controls on the resources that your principals can access. The following table explains the new condition keys and what values these keys can take.
Condition key
Description
Operator
Single/multi value
Value
aws:ResourceOrgID
AWS organization ID of the resource being accessed
Note: Of the three keys, only aws:ResourceOrgPaths is a multi-value condition key, while aws:ResourceAccount and aws:ResourceOrgID are single-value keys. For information on how to use multi-value keys, see Creating a condition with multiple keys or values in the IAM documentation.
Resource owner keys compared to principal owner keys
The new IAM condition keys complement the existing principal condition keys aws:PrincipalAccount, aws:PrincipalOrgPaths, and aws:PrincipalOrgID. The principal condition keys help you define which AWS accounts, organizational units (OUs), and organizations are allowed to access your resources. For more information on the principal conditions, see Use IAM to share your AWS resources with groups of AWS accounts in AWS Organizations on the AWS Security Blog.
Using the principal and resource keys together helps you establish permission guardrails around your AWS principals and resources, and makes it simpler to keep your data inside the organization boundaries you define as you continue to scale. For example, you can define identity-based policies that prevent your IAM principals from accessing resources outside your organization (by using the aws:ResourceOrgID condition). Next, you can define resource-based policies that prevent IAM principals outside your organization from accessing resources that are inside your organization boundary (by using the aws:PrincipalOrgID condition). The combination of both policies prevents any access to and from AWS accounts that are not part of your organization. In the next sections, we’ll walk through an example of how to configure the identity-based policy in your organization. For the resource-based policy, you can follow along with the example in An easier way to control access to AWS resources by using the AWS organization of IAM principals on the AWS Security blog.
Setup for the examples
In the following sections, we’ll show an example IAM policy for each of the new conditions. To follow along with Example 1, which uses aws:ResourceAccount, you’ll just need an AWS account.
To follow along with Examples 2 and 3 that use aws:ResourceOrgPaths and aws:ResourceOrgID respectively, you’ll need to have an organization in AWS Organizations and at least one OU created. This blog post assumes that you have some familiarity with the basic concepts in IAM and AWS Organizations. If you need help creating an organization or want to learn more about AWS Organizations, visit Getting Started with AWS Organizations in the AWS documentation.
Which IAM policy type should I use?
You can implement the following examples as identity-based policies, or in SCPs that are managed in AWS Organizations. If you want to establish a boundary for some of your IAM principals, we recommend that you use identity-based policies. If you want to establish a boundary for an entire AWS account or for your organization, we recommend that you use SCPs. Because SCPs apply to an entire AWS account, you should take care when you apply the following policies to your organization, and account for any exceptions to these rules that might be necessary for some AWS services to function properly.
Example 1: Restrict access to AWS resources within a specific AWS account
Let’s look at an example IAM policy that restricts access along the boundary of a single AWS account. For this example, say that you have an IAM principal in account 222222222222, and you want to prevent the principal from accessing S3 objects outside of this account. To create this effect, you could attach the following IAM policy.
Note: This policy is not meant to replace your existing IAM access controls, because it does not grant any access. Instead, this policy can act as an additional guardrail for your other IAM permissions. You can use a policy like this to prevent your principals from access to any AWS accounts that you don’t know or control, regardless of the permissions granted through other IAM policies.
This policy uses a Deny effect to block access to S3 actions unless the S3 resource being accessed is in account 222222222222. This policy prevents S3 access to accounts outside of the boundary of a single AWS account. You can use a policy like this one to limit your IAM principals to access only the resources that are inside your trusted AWS accounts. To implement a policy like this example yourself, replace account ID 222222222222 in the policy with your own AWS account ID. For a policy you can apply to multiple accounts while still maintaining this restriction, you could alternatively replace the account ID with the aws:PrincipalAccount condition key, to require that the principal and resource must be in the same account (see example #3 in this post for more details how to accomplish this).
Organization setup: Welcome to AnyCompany
For the next two examples, we’ll use an example organization called AnyCompany that we created in AWS Organizations. You can create a similar organization to follow along directly with these examples, or adapt the sample policies to fit your own organization. Figure 1 shows the organization structure for AnyCompany.
Figure 1: Organization structure for AnyCompany
Like all organizations, AnyCompany has an organization root. Under the root are three OUs: Media, Sports, and Governance. Under the Sports OU, there are three more OUs: Baseball, Basketball, and Football. AWS accounts in this organization are spread across all the OUs based on their business purpose. In total, there are six OUs in this organization.
Example 2: Restrict access to AWS resources within my organizational unit
Now that you’ve seen what the AnyCompany organization looks like, let’s walk through another example IAM policy that you can use to restrict access to a specific part of your organization. For this example, let’s say you want to restrict S3 object access within the following OUs in the AnyCompany organization:
Media
Sports
Baseball
Basketball
Football
To define a boundary around these OUs, you don’t need to list all of them in your IAM policy. Instead, you can use the organization structure to your advantage. The Baseball, Basketball, and Football OUs share a parent, the Sports OU. You can use the new aws:ResourceOrgPaths key to prevent access outside of the Media OU, the Sports OU, and any OUs under it. Here’s the IAM policy that achieves this effect.
Note: Like the earlier example, this policy does not grant any access. Instead, this policy provides a backstop for your other IAM permissions, preventing your principals from accessing S3 objects outside an OU-defined boundary. If you want to require that your IAM principals consistently follow this rule, we recommend that you apply this policy as an SCP. In this example, we attached this policy to the root of our organization, applying it to all principals across all accounts in the AnyCompany organization.
The policy denies access to S3 actions unless the S3 resource being accessed is in a specific set of OUs in the AnyCompany organization. This policy is identical to Example 1, except for the condition block: The condition requires that aws:ResourceOrgPaths contains any of the listed OU paths. Because aws:ResourceOrgPaths is a multi-value condition, the policy uses the ForAllValues:StringNotLike operator to compare the values of aws:ResourceOrgPaths to the list of OUs in the policy.
The first OU path in the list is for the Media OU. The second OU path is the Sports OU, but it also adds the wildcard character * to the end of the path. The wildcard * matches any combination of characters, and so this condition matches both the Sports OU and any other OU further down its path. Using wildcards in the OU path allows you to implicitly reference other OUs inside the Sports OU, without having to list them explicitly in the policy. For more information about wildcards, refer to Using wildcards in resource ARNs in the IAM documentation.
Example 3: Restrict access to AWS resources within my organization
Finally, we’ll look at a very simple example of a boundary that is defined at the level of an entire organization. This is the same use case as the preceding two examples (restrict access to S3 object access), but scoped to an organization instead of an account or collection of OUs.
Note: Like the earlier examples, this policy does not grant any access. Instead, this policy provides a backstop for your other IAM permissions, preventing your principals from accessing S3 objects outside your organization regardless of their other access permissions. If you want to require that your IAM principals consistently follow this rule, we recommend that you apply this policy as an SCP. As in the previous example, we attached this policy to the root of our organization, applying it to all accounts in the AnyCompany organization.
The policy denies access to S3 actions unless the S3 resource being accessed is in the same organization as the IAM principal that is accessing it. This policy is identical to Example 1, except for the condition block: The condition requires that aws:ResourceOrgID and aws:PrincipalOrgID must be equal to each other. With this requirement, the principal making the request and the resource being accessed must be in the same organization. This policy also applies to S3 resources that are created after the policy is put into effect, so it is simple to maintain the same security posture across all your resources.
In this post, we explored the new conditions, and walked through a few examples to show you how to restrict access to S3 objects across the boundary of an account, OU, or organization. These tools work for more than just S3, though: You can use the new conditions to help you protect a wide variety of AWS services and actions. Here are a few links that you may want to look at:
Whitepaper: Building an AWS Perimeter provides an in-depth overview of how to use these keys as part of a broader strategy to secure your AWS resources.
If you have any questions, comments, or concerns, contact AWS Support or start a new thread on the AWS Identity and Access Management forum. Thanks for reading about this new feature. If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security news? Follow us on Twitter.
Git hooks are scripts that extend Git functionality when certain events and actions occur during code development. Developer teams often use Git hooks to perform quality checks before they commit their code changes. For example, see the blog post Use Git pre-commit hooks to avoid AWS CloudFormation errors for a description of how the AWS Integration and Automation team uses various pre-commit hooks to help reduce effort and errors when they build AWS Quick Starts.
This blog post shows you how to extend your Git hooks to validate your AWS CloudFormation templates against policy-as-code rules by using AWS CloudFormation Guard. This can help you verify that your code follows organizational best practices for security, compliance, and more by preventing you from commit changes that fail validation rules.
We will also provide patterns you can use to centrally maintain a list of rules that security teams can use to roll out new security best practices across an organization. You will learn how to configure a pre-commit framework by using an example repository while you store Guard rules in both a central Amazon Simple Storage Service (Amazon S3) bucket or in versioned code repositories (such as AWS CodeCommit, GitHub, Bitbucket, or GitLab).
Prerequisites
To complete the steps in this blog post, first perform the following installations.
In this section, we walk you through an exercise to extend a Java service on an Amazon EKS example repository with Git hooks by using AWS CloudFormation Guard. You can choose to upload your Guard rules in either a separate GitHub repository or your own S3 bucket.
First, download the sample repository that you will add the pre-commit framework to.
To clone the test repository
Clone the repo to a local directory by running the following command in your local terminal.
where <account-id> is the ID of the AWS account you’re using and <aws-region> is the AWS Region you want to use.
(Optional) Alternatively, you can follow the Getting started with Amazon S3 tutorial to create the bucket and upload the object (as described in step 4 that follows) by using the AWS Management Console.
When you store your Guard rules in an S3 bucket, you can make the rules accessible to other member accounts in your organization by using the aws:PrincipalOrgID condition and setting the value to your organization ID in the bucket policy.
Create a file that contains a Guard rule named rules.guard, with the following content.
let eks_cluster = Resources.* [ Type == 'AWS::EKS::Cluster' ]
rule eks_public_disallowed when %eks_cluster !empty {
      %eks_cluster.Properties.ResourcesVpcConfig.EndpointPublicAccess == false
}
This rule will verify that public endpoints are disabled by checking that resources that are created by using the AWS::EKS::Cluster resource type have the EndpointPublicAccess property set to false. For more information about authoring your own rules using Guard domain-specific language (DSL), see Introducing AWS CloudFormation Guard 2.0.
Upload the rule set to your S3 bucket by running the following command in the AWS CLI.
In the next step, you will set up the pre-commit framework in the repository to run CloudFormation Guard against code changes.
To configure your pre-commit hook to use Guard
Run the following command to create a new branch where you will test your changes. git checkout -b feature/guard-hook
Navigate to the root directory of the project that you cloned earlier and create a .pre-commit-config.yaml file with the following configuration.
repos:
  - repo: local
    hooks:
      -   id: cfn-guard-rules
          name: Rules for AWS
          description: Download Organization rules
          entry: aws s3 cp --recursive s3://<account-id>-cfn-guard-rules/rules  guard-rules/org-rules/
          language: system
          pass_filenames: false
      -   id: cfn-guard
          name: AWS CloudFormation Guard
          description: Validate code against your Guard rules
          entry: bash -c 'for template in "$@"; do cfn-guard validate -r guard-rules -d "$template" || SCAN_RESULT="FAILED"; done; if [[ "$SCAN_RESULT" = "FAILED" ]]; then exit 1; fi'
          language: rust
          files: \.(json|yaml|yml|template\.json|template)$
          additional_dependencies:
            - cli:cfn-guard
You will need to replace the <account-id> placeholder value with the AWS account ID you entered in the To set up an S3 bucket with your Guard rules procedure.
This hook configuration uses local pre-commit hooks to download the latest version of Guard rules from the bucket you created previously. This allows you to set up a centralized set of Guard rules across your organization.
Alternatively, you can create and use a code repository such as GitHub, AWS CodeCommit, or Bitbucket to keep your rules in version control. To do so, replace the command in the Download Organization rules step of the .pre-commit-config.yaml file with:
bash -c ‘if [ -d guard-rules/org-rules ]; then cd guard-rules/org-rules && git pull; else git clone <guard-rules-repository-target> guard-rules/org-rules; fi’
Where <guard-rules-repository-target> is the HTTPS or SSH URL of your repository. This command will clone or pull the latest rules from your Git repo by using your Git credentials.
The hook will also install Guard as an additional dependency by using a Rust hook. Using Guard, it will run the code changes in the repository directory against the downloaded rule set. When misconfigurations are detected, the hook stops the commit.
You can further extend your organization rules with your own Guard rules by adding them to the cfn-guard-rules folder. You should commit these rules in your repository and add cfn-guard-rules/org-rules/* to your .gitignore file.
Run a pre-commit install command to install the hooks you just created.
Finally, test that the pre-commit’s Guard hook fails commits of code changes that do not follow organizational best practices.
To test pre-commit hooks
Add EndpointPublicAccess: true in cloudformation/eks.template.yaml, as shown following. This describes the test-only intent (meaning that you want to detect and flag errors in your rule) of adding public access to the Amazon Elastic Kubernetes Service (Amazon EKS) cluster.
You should see the following error that disallows the commit to the local repository and shows which one of your Guard rules failed.
amazon-eks-controlplane.template.yaml Status = FAIL

FAILED rules

rules.guard/eks_public_disallowed    FAIL

---

Evaluation of rules rules.guard against data amazon-eks-controlplane.template.yaml

---

Property
[/Resources/EKS/Properties/ResourcesVpcConfig/EndpointPublicAccess] in data
[eks.template.yaml] is not compliant with [rules.guard/eks_public_disallowed]
because provided value [true] did not match expected value [false].
Error Message []
(Optional) You can also test hooks before committing by using the pre-commit run command to see similar output.
Cleanup
To avoid incurring ongoing charges, follow these cleanup steps to delete the resources and files you created as you followed along with this blog post.
To clean up resources and files
Remove your local repository.
rm -rf /path/to/repository
Delete the S3 bucket you created by running the following command.
(Optional) Remove the pre-commit hooks framework by running this command.
pip uninstall pre-commit
Conclusion
In this post, you learned how to use AWS CloudFormation Guard with the pre-commit framework locally to validate your infrastructure-as-code solutions before you push remote changes to your repositories.
You also learned how to extend the solution to use a centralized list of security rules that is stored in versioned code repositories (GitHub, Bitbucket, or GitLab) or an S3 bucket. And you learned how to further extend the solution with your own rules. You can find examples of rules to use in Guard’s Github repository or refer to write preventative compliance rules for AWS CloudFormation templates the cfn-guard way. You can then further configure other repositories to prevent misconfigurations by using the same Guard rules.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the KMS re:Post or contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
The General Data Protection Law (LGPD) in Brazil was first published on 14 August 2018, and started its applicability on 18 August 2020. Companies that manage personally identifiable information (PII) in Brazil as defined by LGPD will have to comply with and attend to the law.
To better help customers prepare and implement controls that focus on LGPD Chapter VII Security and Best Practices, AWS created a workbook based on industry best practices, AWS service offerings, and controls.
Amongst other topics, this workbook covers information security and AWS controls from:
AWS adheres to a shared responsibility model. Customers will have to observe which services offer privacy features and determine their applicability to their specific compliance requirements. Further information about data privacy at AWS can be found at our Data Privacy Center. Specific information about LGPD and data privacy at AWS in Brazil can be found on our Brazil Data Privacy page.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
If you have feedback about this post, submit comments in the Comments section below. Want more AWS Security news? Follow us on Twitter.
Portuguese
Workbook da LGPD para Clientes AWS que gerenciam Informações de Identificação Pessoal no Brasil
A Lei Geral de Proteção de Dados (LGPD) teve sua primeira publicação em 14 de agosto de 2018 no Brasil e iniciou sua aplicabilidade em 18 de agosto de 2020. Empresas que gerenciam informações pessoais identificáveis (PII) conforme definido na LGPD terão que cumprir e atender às cláusulas da lei.
Para ajudar melhor os clientes a preparar e implementar controles que se concentram no Capítulo VII da LGPD “da Segurança e Boas Práticas”, a AWS criou uma pasta de trabalho com base nas melhores práticas do setor, ofertas de serviços e controles da AWS.
Entre outros tópicos, esta pasta de trabalho aborda a segurança da informação e os controles da AWS de:
CIS v8.0 – framework contendo 18 domínios de controles
NIST Cybersecurity Framework (CSF) – informações adicionais sobre NIST CSF disponíveis para consulta
Para saber mais sobre nossos programas de conformidade e segurança, consulte Programas de conformidade da AWS. Como sempre, valorizamos seus comentários e perguntas; entre em contato com a equipe de conformidade da AWS por meio da página Fale conosco.
Se você tiver feedback sobre esta postagem, envie comentários na seção Comentários abaixo.
Quer mais notícias sobre segurança da AWS? Siga-nos no Twitter.
Amazon Web Services (AWS) welcomes the new Trans-Atlantic Data Privacy Framework (Data Privacy Framework) that was agreed to, in principle, between the European Union (EU) and the United States (US) last month. This announcement demonstrates the common will between the US and EU to strengthen privacy protections in trans-Atlantic data flows, and will supplement the safeguards AWS and other companies already offer today. AWS commits to undertaking certification in accordance with the Data Privacy Framework as it is adopted, and we look forward to our customers and their end users benefiting from the new safeguards.
The Data Privacy Framework, once finalized, will re-establish a mechanism for certified businesses to conduct trans-Atlantic data transfers between the US and EU. According to the announcement, the new Data Privacy Framework will address the concerns raised by the Court of Justice of the European Union (CJEU) when it invalidated the EU-US Privacy Shield in its Schrems II decision in uly 2020. The Data Privacy Framework will adopt new safeguards to ensure that US intelligence activities are limited to what is necessary and proportionate to protect national security, and also create a new redress system to address the complaints of EU citizens.
As one of the architects of the Trusted Cloud Principles (a cloud-industry initiative to help safeguard the interests of organizations and the basic rights of individuals using cloud), AWS fully supports improved rules and regulations that advance privacy and security protections for any organization that wants to use cloud technologies and maintain control of their data.
While organizations using AWS technology have been able to conduct trans-Atlantic data transfers even after Schrems II, the new Data Privacy Framework will ensure further clarity and agility for our customers in their data transfer assessments. This will help our customers unlock value in terms of growth, digital transformation, and global competitive advantage.
More than ever, our collective security requires mutual trust across both sides of the Atlantic and beyond. We therefore look forward to participating in, and remain committed to, the finalization of the Data Privacy Framework. We also support efforts to build broad consensus around the appropriate balance between privacy and security in forums such as the OECD’s workstream on trusted government access to data held by the private sector.
About AWS privacy and security
AWS is committed to protecting customer data. We continue to help customers successfully meet evolving European laws and standards, and achieve the highest levels of security, privacy, and resilience. AWS already offers comprehensive technical, operational, and contractual measures to protect and transfer customer content outside of Europe in compliance with the General Data Protection Regulation (GDPR) and the Schrems II ruling. Customers can also choose to store their content in the European Union by selecting any one or more of our regions in France, Germany, Ireland, Italy, Sweden, and later in 2022, Spain, with the confidence that their data stays in the AWS Region they select. In addition, customers can use an advanced set of access, encryption, and logging features to maintain full control of their content.
Today, AWS customers can also transfer their data outside of the European Economic Area (EEA) by relying on the new Standard Contractual Clauses (SCCs) included in the AWS Data Processing Addendum (DPA), which is supplemented by our strengthened contractual commitments to protect customer data, such as challenging law enforcement requests that conflict with EU law.
We also have a wide variety of tools available to enhance the security of cross-border data transfers for customers with global services. For example, AWS CloudHSM and AWS Key Management Service (AWS KMS) allow customers to encrypt data in transit and at rest, and securely generate and manage control of encryption keys. By building on top of the AWS Nitro System, our answer to confidential computing, which includes the use of specialized hardware and associated firmware to protect customer code and data during processing from outside access, customers can further secure data during processing, and thereby enhance confidentiality and privacy.
As well as benefitting from these existing measures, our extensive online resources can help customers more easily complete data-transfer assessments and fulfill their GDPR compliance requirements, in accordance with the European Data Protection Board (EDPB) recommendations. This includes regular Information Request Reports showing requests to access data from governments and our responses.
At Amazon Web Services (AWS), we are committed to providing continued assurance to our customers through assessments, certifications, and attestations that support the adoption of AWS services. We are pleased to announce the availability of the Canadian Centre for Cyber Security (CCCS) assessment summary report for AWS, which you can view and download on demand through AWS Artifact.
The CCCS is Canada’s authoritative source of cyber security expert guidance for the Canadian government, industry, and the general public. Public and commercial sector organizations across Canada rely on CCCS’s rigorous Cloud Service Provider (CSP) IT Security (ITS) assessment in their decision to use CSP services. In addition, CCCS’s ITS assessment process is a mandatory requirement for AWS to provide cloud services to Canadian federal government departments and agencies.
The CCCS Cloud Service Provider Information Technology Security Assessment Process determines if the Government of Canada (GC) ITS requirements for the CCCS Medium Cloud Security Profile (previously referred to as GC’s PROTECTED B/Medium Integrity/Medium Availability [PBMM] profile) are met as described in ITSG-33 (IT Security Risk Management: A Lifecycle Approach, Annex 3 – Security Control Catalogue). As of September, 2021, 120 AWS services in the Canada (Central) Region have been assessed by the CCCS, and meet the requirements for medium cloud security profile. Meeting the medium cloud security profile is required to host workloads that are classified up to and including medium categorization. On a periodic basis, CCCS assesses new or previously unassessed services and re-assesses the AWS services that were previously assessed to verify that they continue to meet the GC’s requirements. CCCS prioritizes the assessment of new AWS services based on their availability in Canada, and customer demand for the AWS services. The full list of AWS services that have been assessed by CCCS is available on our Services in Scope by Compliance Program page.
To learn more about the CCCS assessment or our other compliance and security programs, visit AWS Compliance Programs. If you have questions about this blog post, please start a new thread on the AWS Artifact forum or contact AWS Support.
If you have feedback about this post, submit comments in the Comments section below. Want more AWS Security news? Follow us on Twitter.
.
Rapport sommaire de l’évaluation du Centre canadien pour la cybersécurité disponible sur AWS Artifact
Par Robert Samuel, Naranjan Goklani et Brian Mycroft Amazon Web Services (AWS) s’engage à fournir à ses clients une assurance continue à travers des évaluations, des certifications et des attestations qui appuient l’adoption des services proposés par AWS. Nous avons le plaisir d’annoncer la mise à disposition du rapport sommaire de l’évaluation du Centre canadien pour la cybersécurité (CCCS) pour AWS, que vous pouvez dès à présent consulter et télécharger à la demande sur AWS Artifact.
Le CCC est l’autorité canadienne qui met son expertise en matière de cybersécurité au service du gouvernement canadien, du secteur privé et du grand public. Les organisations des secteurs public et privé établies au Canada dépendent de la rigoureuse évaluation de la sécurité des technologies de l’information s’appliquant aux fournisseurs de services infonuagiques conduite par le CCC pour leur décision relative à l’utilisation de ces services infonuagiques. De plus, le processus d’évaluation de la sécurité des technologies de l’information est une étape obligatoire pour permettre à AWS de fournir des services infonuagiques aux agences et aux ministères du gouvernement fédéral canadien.
Le Processus d’évaluation de la sécurité des technologies de l’information s’appliquant aux fournisseurs de services infonuagiques détermine si les exigences en matière de technologie de l’information du Gouvernement du Canada (GC) pour le profil de contrôle de la sécurité infonuagique moyen (précédemment connu sous le nom de Protégé B/Intégrité moyenne/Disponibilité moyenne) sont satisfaites conformément à l’ITSG-33 (Gestion des risques liés à la sécurité des TI : Une méthode axée sur le cycle de vie, Annexe 3 – Catalogue des contrôles de sécurité). En date de septembre 2021, 120 services AWS de la région (centrale) du Canada ont été évalués par le CCC et satisfont aux exigences du profil de sécurité moyen du nuage. Satisfaire les exigences du niveau moyen du nuage est nécessaire pour héberger des applications classées jusqu’à la catégorie moyenne incluse. Le CCC évalue périodiquement les nouveaux services, ou les services qui n’ont pas encore été évalués, et réévalue les services AWS précédemment évalués pour s’assurer qu’ils continuent de satisfaire aux exigences du Gouvernement du Canada. Le CCC priorise l’évaluation des nouveaux services AWS selon leur disponibilité au Canada et en fonction de la demande des clients pour les services AWS. La liste complète des services AWS évalués par le CCC est consultable sur notre page Services AWS concernés par le programme de conformité.
Pour en savoir plus sur l’évaluation du CCC ainsi que sur nos autres programmes de conformité et de sécurité, visitez la page Programmes de conformité AWS. Comme toujours, nous accordons beaucoup de valeur à vos commentaires et à vos questions; vous pouvez communiquer avec l’équipe Conformité AWS via la page Communiquer avec nous.
Si vous avez des commentaires sur cette publication, n’hésitez pas à les partager dans la section Commentaires ci-dessous. Vous souhaitez en savoir plus sur AWS Security? Retrouvez-nous sur Twitter.
Biographies des auteurs :
Rob Samuel : Rob Samuel est responsable technique principal d’AWS Security Assurance. Il collabore avec les équipes AWS pour traduire les principes de protection des données en recommandations techniques, aligne la direction technique et les priorités, met en œuvre les nouvelles solutions techniques, aide à intégrer les solutions de sécurité et de confidentialité aux services et fonctionnalités proposés par AWS et répond aux exigences et aux attentes en matière de confidentialité et de sécurité transversale. Rob a plus de 20 ans d’expérience dans le secteur de la technologie et a déjà occupé des fonctions dirigeantes, comme directeur de l’assurance sécurité pour AWS Canada, responsable de la cybersécurité et des systèmes d’information (RSSI) pour la province de la Nouvelle-Écosse, divers postes à responsabilités en tant que fonctionnaire et a servi dans les Forces armées canadiennes en tant qu’officier du génie électronique et des communications.
Naranjan Goklani : Naranjan Goklani est responsable des audits de sécurité pour AWS, il est basé à Toronto (Canada). Il est responsable des audits, des attestations, des certifications et des évaluations pour l’Amérique du Nord et l’Europe. Naranjan a plus de 12 ans d’expérience dans la gestion des risques, l’assurance de la sécurité et la réalisation d’audits de technologie. Naranjan a exercé dans l’une des quatre plus grandes sociétés de comptabilité et accompagné des clients des industries de la distribution, du commerce en ligne et des services publics.
Brian Mycroft : Brian Mycroft est technologue en chef pour AWS, il est basé à Ottawa (Canada) et se spécialise dans la sécurité nationale, le renseignement et le gouvernement fédéral du Canada. Brian est l’architecte principal de l’AWS Secure Environment Accelerator (ASEA) et s’intéresse principalement à la suppression des barrières à l’adoption du nuage pour le secteur public.
Today AWS Key Management Service (AWS KMS) is introducing new APIs to generate and verify hash-based message authentication codes (HMACs) using the Federal Information Processing Standard (FIPS) 140-2 validated hardware security modules (HSMs) in AWS KMS. HMACs are a powerful cryptographic building block that incorporate secret key material in a hash function to create a unique, keyed message authentication code.
In this post, you will learn the basics of the HMAC algorithm as a cryptographic building block, including how HMACs are used. In the second part of this post, you will see a few real-world use cases that show an application builder’s perspective on using the AWS KMS HMAC APIs.
HMACs provide a fast way to tokenize or sign data such as web API requests, credit cards, bank routing information, or personally identifiable information (PII).They are commonly used in several internet standards and communication protocols such as JSON Web Tokens (JWT), and are even an important security component for how you sign AWS API requests.
HMAC as a cryptographic building block
You can consider an HMAC, sometimes referred to as a keyed hash, to be a combination function that fuses the following elements:
A standard hash function such as SHA-256 to produce a message authentication code (MAC).
A secret key that binds this MAC to that key’s unique value.
Combining these two elements creates a unique, authenticated version of the digest of a message. Because the HMAC construction allows interchangeable hash functions as well as different secret key sizes, one of the benefits of HMACs is the easy replaceability of the underlying hash function (in case faster or more secure hash functions are required), as well as the ability to add more security by lengthening the size of the secret key used in the HMAC over time. The AWS KMS HMAC API is launching with support for SHA-224, SHA-256, SHA-384, and SHA-512 algorithms to provide a good balance of key sizes and performance trade-offs in the implementation. For more information about HMAC algorithms supported by AWS KMS, see HMAC keys in AWS KMS in the AWS KMS Developer Guide.
HMACs offer two distinct benefits:
Message integrity: As with all hash functions, the output of an HMAC will result in precisely one unique digest of the message’s content. If there is any change to the data object (for example you modify the purchase price in a contract by just one digit: from “$350,000” to “$950,000”), then the verification of the original digest will fail.
Message authenticity: What distinguishes HMAC from other hash methods is the use of a secret key to provide message authenticity. Only message hashes that were created with the specific secret key material will produce the same HMAC output. This dependence on secret key material ensures that no third party can substitute their own message content and create a valid HMAC without the intended verifier detecting the change.
HMAC in the real world
HMACs have widespread applications and industry adoption because they are fast, high performance, and simple to use. HMACs are particularly popular in the JSON Web Token (JWT) open standard as a means of securing web applications, and have replaced older technologies such as cookies and sessions. In fact, Amazon implements a custom authentication scheme, Signature Version 4 (SigV4), to sign AWS API requests based on a keyed-HMAC. To authenticate a request, you first concatenate selected elements of the request to form a string. You then use your AWS secret key material to calculate the HMAC of that string. Informally, this process is called signing the request, and the output of the HMAC algorithm is informally known as the signature, because it simulates the security properties of a real signature in that it represents your identity and your intent.
Advantages of using HMACs in AWS KMS
AWS KMS HMAC APIs provide several advantages over implementing HMACs in application software because the key material for the HMACs is generated in AWS KMS hardware security modules (HSMs) that are certified under the FIPS 140-2 program and never leave AWS KMS unencrypted. In addition, the HMAC keys in AWS KMS can be managed with the same access control mechanisms and auditing features that AWS KMS provides on all AWS KMS keys. These security controls ensure that any HMAC created in AWS KMS can only ever be verified in AWS KMS using the same KMS key. Lastly, the HMAC keys and the HMAC algorithms that AWS KMS uses conform to industry standards defined in RFC 2104 HMAC: Keyed-Hashing for Message Authentication.
Use HMAC keys in AWS KMS to create JSON Web Tokens
The JSON Web Token (JWT) open standard is a common use of HMAC. The standard defines a portable and secure means to communicate a set of statements, known as claims, between parties. HMAC is useful for applications that need an authorization mechanism, in which claims are validated to determine whether an identity has permission to perform some action. Such an application can only work if a validator can trust the integrity of claims in a JWT. Signing JWTs with an HMAC is one way to assert their integrity. Verifiers with access to an HMAC key can cryptographically assert that the claims and signature of a JWT were produced by an issuer using the same key.
This section will walk you through an example of how you can use HMAC keys from AWS KMS to sign JWTs. The example uses the AWS SDK for Python (Boto3) and implements simple JWT encoding and decoding operations. This example shows the ease with which you can integrate HMAC keys in AWS KMS into your JWT application, even if your application is in another language or uses a more formal JWT library.
Create an HMAC key in AWS KMS
Begin by creating an HMAC key in AWS KMS. You can use the AWS KMS console or call the CreateKey API action. The following example shows creation of a 256-bit HMAC key:
import boto3

kms = boto3.client('kms')

# Use CreateKey API to create a 256-bit key for HMAC
key_id = kms.create_key(
	KeySpec='HMAC_256',
	KeyUsage='GENERATE_VERIFY_MAC'
)['KeyMetadata']['KeyId']
Use the HMAC key to encode a signed JWT
Next, you use the HMAC key to encode a signed JWT. There are three components to a JWT token: the set of claims, header, and signature. The claims are the very application-specific statements to be authenticated. The header describes how the JWT is signed. Lastly, the MAC (signature) is the output of applying the header’s described operation to the message (the combination of the claims and header). All these are packed into a URL-safe string according to the JWT standard.
The following example uses the previously created HMAC key in AWS KMS within the construction of a JWT. The example’s claims simply consist of a small claim and an issuance timestamp. The header contains key ID of the HMAC key and the name of the HMAC algorithm used. Note that HS256 is the JWT convention used to represent HMAC with SHA-256 digest. You can generate the MAC using the new GenerateMac API action in AWS KMS.
import base64
import json
import time

def base64_url_encode(data):
	return base64.b64encode(data, b'-_').rstrip(b'=')

# Payload contains simple claim and an issuance timestamp
payload = json.dumps({
	"does_kms_support_hmac": "yes",
	"iat": int(time.time())
}).encode("utf8")

# Header describes the algorithm and AWS KMS key ID to be used for signing
header = json.dumps({
	"typ": "JWT",
	"alg": "HS256",
	"kid": key_id #This key_id is from the “Create an HMAC key in AWS KMS” #example. The “Verify the signed JWT” example will later #assert that the input header has the same value of the #key_id
}).encode("utf8")

# Message to sign is of form <header_b64>.<payload_b64>
message = base64_url_encode(header) + b'.' + base64_url_encode(payload)

# Generate MAC using GenerateMac API of AWS KMS
MAC = kms.generate_mac(
	KeyId=key_id, #This key_id is from the “Create an HMAC key in AWS KMS”
				 #example
	MacAlgorithm='HMAC_SHA_256',
	Message=message
)['Mac']

# Form JWT token of form <header_b64>.<payload_b64>.<mac_b64>
jwt_token = message + b'.' + base64_url_encode(mac)
Verify the signed JWT
Now that you have a signed JWT, you can verify it using the same KMS HMAC key. The example below uses the new VerifyMac API action to validate the MAC (signature) of the JWT. If the MAC is invalid, AWS KMS returns an error response and the AWS SDK throws an exception. If the MAC is valid, the request succeeds and the application can continue to do further processing on the token and its claims.
def base64_url_decode(data):
	return base64.b64decode(data + b'=' * (4 - len(data) % 4), b'-_')

# Parse out encoded header, payload, and MAC from the token
message, mac_b64 = jwt_token.rsplit(b'.', 1)
header_b64, payload_b64 = message.rsplit(b'.', 1)

# Decode header and verify its contents match expectations
header_map = json.loads(base64_url_decode(header_b64).decode("utf8"))
assert header_map == {
	"typ": "JWT",
	"alg": "HS256",
	"kid": key_id #This key_id is from the “Create an HMAC key in AWS KMS”
				 #example
}

# Verify the MAC using VerifyMac API of AWS KMS. # If the verification fails, this will throw an error.
kms.verify_mac(
	KeyId=key_id, #This key_id is from the “Create an HMAC key in AWS KMS”
				 #example
	MacAlgorithm='HMAC_SHA_256',
	Message=message,
	Mac=base64_url_decode(mac_b64)
)

# Decode payload for use application-specific validation/processing
payload_map = json.loads(base64_url_decode(payload_b64).decode("utf8"))
Create separate roles to control who has access to generate HMACs and who has access to validate HMACs
It’s often helpful to have separate JWT creators and validators so that you can distinguish between the roles that are allowed to create tokens and the roles that are allowed to verify tokens. HMAC signatures performed outside of AWS-KMS don’t work well for this because you can’t isolate creators and verifiers if they both must have a copy of the same key. However, this is not an issue for HMAC keys in AWS KMS. You can use key policies to separate out who has permission to ask AWS KMS to generate HMACs and who has permission to ask AWS KMS to validate. Each party uses their own unique access keys to access the HMAC key in AWS KMS. Only HSMs in AWS KMS will ever have access to the actual key material. See the following example key policy statements that separate out GenerateMac and VerifyMac permissions:
{
	"Id": "example-jwt-policy",
	"Version": "2012-10-17",
	"Statement": [
		{
			"Sid": "Allow use of the key for creating JWTs",
			"Effect": "Allow",
			"Principal": {
				"AWS": "arn:aws:iam::111122223333:role/JwtProducer"
			},
			"Action": [
				"kms:GenerateMac"
			],
			"Resource": "*"
		},
		{
			"Sid": "Allow use of the key for validating JWTs",
			"Effect": "Allow",
			"Principal": {
				"AWS": "arn:aws:iam::111122223333:role/JwtConsumer"
			},
			"Action": [
				"kms:VerifyMac"
			],
			"Resource": "*"
		}
	]
}
Conclusion
In this post, you learned about the new HMAC APIs in AWS KMS (GenerateMac and VerifyMac). These APIs complement existing AWS KMS cryptographic operations: symmetric key encryption, asymmetric key encryption and signing, and data key creation and key enveloping. You can use HMACs for JWTs, tokenization, URL and API signing, as a key derivation function (KDF), as well as in new designs that we haven’t even thought of yet. To learn more about HMAC functionality and design, see HMAC keys in AWS KMS in the AWS KMS Developer Guide.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the KMS re:Post or contact AWS Support. Want more AWS Security news? Follow us on Twitter.
We are pleased to announce that in all AWS Regions that support Amazon Cognito, you can now integrate Amazon Cognito with Amazon Simple Email Service (Amazon SES) and Amazon Simple Notification Service (Amazon SNS) in the same Region. By integrating these services in the same Region, you can more easily achieve lower latency, and remove cross-Region dependencies in your architecture. Amazon Cognito lets you add authentication, authorization, and user management to your web and mobile apps. Amazon Cognito scales to millions of users and supports sign-in with social identity providers such as Apple, Facebook, Google, and Amazon, and enterprise identity providers that support SAML 2.0 and OpenID Connect (OIDC).
Amazon Cognito launched new console experience in 2021 that makes it even easier for you to manage Amazon Cognito user pools and add sign-in and sign-up functionality to your applications. The new console has now been further enhanced to configure the in-Region Amazon SES options as shown in Figure 1, and Amazon SNS options as shown in Figure 2. Also you can configure the same via Amazon Cognito APIs. Thus you can update your in-Region Amazon SES, Amazon SNS configuration options through the console, API, or CLI. You can use Amazon Cognito in a Region that suits your business requirements and sustainability goals, and extend your Amazon Cognito architecture to additional Regions.
Figure 1: Amazon SES Region drop-down selection with new options
Figure 2: Amazon SNS Region selection drop-down selection with new options
In-Region integration with Amazon SES and Amazon SNS is currently available in all Regions where Amazon SES, Amazon SNS and Amazon Cognito are available. For up to date information, see the AWS Regional Services List. To learn more, see What is Amazon Cognito?.
Frequently asked questions (FAQs)
What Region will Amazon Cognito console default to when I configure Amazon SES and Amazon SNS Regions?
When creating new user pools, the Amazon Cognito console auto-populates the Region to in-Region, but you still have to select the identity. Existing user pools with cross-Region Amazon SES or Amazon SNS integration will not be affected.
Can I update an existing user pool to integrate with Amazon SES or Amazon SNS in the same Region?
Yes, you can change your configuration so that Amazon Cognito integrates with either Amazon SES or Amazon SNS, or both, in the same Region.
What Regions can I use with Amazon Cognito for Amazon SNS and Amazon SES?
Why should I change from cross-Region to same-Region Amazon SES or Amazon SNS?
Amazon Cognito is designed to scale to millions of users. Your users expect prompt delivery of their messages for multi-factor authentication and account setup. Using Amazon SES and Amazon SNS in the same Region as your user pool improves performance by reducing the round-trip time of the call that Amazon Cognito makes to Amazon SES or Amazon SNS.
What are the key benefits of using in-Region integration?
Availability: Availability is improved as you no longer will have cross-Region dependency for Amazon SES or Amazon SNS.
Latency: Transit time for API requests is most efficient within a single AWS Region.
Usability: Billing, logging, and setup are more transparent when you consolidate resources in the same Region.
Which version of Amazon Cognito user pools console does this change apply to?
This change applies to current version of the new Amazon Cognito user pool console experience. Also this change applies to current version of Amazon Cognito APIs.
Will my current cross-Region integration change?
No. Your AWS resources are your own and will not be changed. If you want to make use of the new in-Region integration, you must update your user pool configuration to integrate with Amazon SES or Amazon SNS in the same AWS Region.
Will I be placed in the SMS sandbox if I change my Amazon SNS Region?
The SMS sandbox status is Region dependent, so whether or not your user pool is in the SMS sandbox depends on the SNS Region you configure in your user pool. When your account is in the SMS sandbox, Amazon Cognito can send SMS text messages only to verified phone numbers and not to all of your users. When you move to a new Region, verified phone numbers will also need to be re-verified. For more information, see SMS message settings for Amazon Cognito user pools.
To find info about whether your user pool is configured in an SNS Region that is in the SMS sandbox, you can view the SmsConfigurationFailure field in DescribeUserPool API.
Which API parameters can developers use to make the in-Region changes?
Will my automation scripts break due to this change?
This change to support in-Region integration will not break your automation scripts. If future updates include changing the default Region value to in-Region, we plan to inform all Amazon Cognito customers about this change with sufficient time to transition to the new default Region value.
Can I revert to my original Region integration if I run into an issue?
Yes, the ability to use Amazon SES or Amazon SNS resources in a different AWS Region is still supported.
Next steps
If your Amazon Cognito user pool is currently configured to make cross-Region calls to Amazon SES or Amazon SNS, you can update your configuration through the console, API, or CLI.
If you have any questions or issues, you can start a new thread on AWS re:Post, contact AWS Support, or your technical account manager (TAM).
Want more AWS Security news? Follow us on Twitter.
You can use third-party identity providers (IdPs) such as Okta, Ping, or OneLogin to federate with the AWS Identity and Access Management (IAM) service using SAML 2.0, allowing your workforce to configure services by providing authorization access to the AWS Management Console or Command Line Interface (CLI). When you federate to AWS, you assume a role through the AWS Security Token Service (AWS STS), which through the AssumeRole API returns a set of temporary security credentials you then use to access AWS resources. The use of temporary credentials can make it challenging for administrators to trace which identity was responsible for actions performed.
To address this, with AWS STS you set a unique attribute called SourceIdentity, which allows you to easily see which identity is responsible for a given action.
This post will show you how to set up the AWS STS SourceIdentity attribute when using Okta, Ping, or OneLogin as your IdP. Your IdP administrator can configure a corporate directory attribute, such as an email address, to be passed as the SourceIdentity value within the SAML assertion. This value is stored as the SourceIdentity element in AWS CloudTrail, along with the activity performed by the assumed role. This post will also show you how to set up a sample policy for setting the SourceIdentity when switching roles. Finally, as an administrator reviewing CloudTrail activity, you can use the source identity information to determine who performed which actions. We will walk you through CloudTrail logs from two accounts to demonstrate the continuance of the source identity attribute, showing you how the SourceIdentity will appear in both accounts’ logs.
Configure the SourceIdentity attribute with Okta integration
You will do this portion of the configuration within the Okta administrative console. This procedure assumes that you have a previously configured AWS and Okta integration. If not, you can configure your integration by following the instructions in the Okta AWS Multi-Account Configuration Guide. You will use the Okta to SAML integration and configure an optional attribute to map as the SourceIdentity.
To set up Okta with SourceIdentity
Log in to the Okta admin console.
Navigate to Applications–AWS.
In the top navigation bar, select the Sign On tab, as shown in Figure 1.
Figure 1 – Navigate to attributes in SAML settings on the Okta applications page
Under Sign on methods, select SAML 2.0, and choose the arrow next to Attributes (Optional) to expand, as shown in Figure 2.
Figure 2 – Add new attribute SourceIdentity and map it to Okta provided attribute of your choice
Add the optional attribute definition for SourceIdentity using the following parameters:
For Name, enter: https://aws.amazon.com/SAML/Attributes/SourceIdentity
For Name format, choose URI Reference.
For Value, enter user.login.
Note: The Name format options are the following: Unspecified – can be any format defined by the Okta profile and must be interpreted by your application. URI Reference – the name is provided as a Uniform Resource Identifier string. Basic – a simple string; the default if no other format is specified.
The examples shown in Figure 1 and Figure 2 show how to map an email address to the SourceIdentity attribute by using an on-premises Active Directory sync. The SourceIdentity can be mapped to other attributes from your Active Directory.
Configure the SourceIdentity attribute with PingOne integration
You do this portion of the configuration in the Ping Identity administrative console. This procedure assumes that you have a previously configured AWS and Ping integration. If not, you can set up the PingFederate AWS Connector by following the Ping Identity instructions Configuring an SSO connection to Amazon Web Services.
You’re using the Ping to SAML integration and configuring an optional attribute to map as the source identity.
Configuring PingOne as an IdP involves setting up an identity repository (in this case, the PingOne Directory), creating a user group, and adding users to the individual groups.
Choose the My Applications tab, as shown in Figure 3.
Figure 3. PingOne My Applications tab
On the Amazon Web Services line, choose on the arrow on the right side to show application details to edit and add a new attribute for the source identity.
Choose Continue to Next Step to open the Attribute Mapping section, as shown in Figure 4.
Figure 4. Attribute mappings
In the Attribute Mapping section line 1, for SAML_SUBJECT, choose Advanced.
On the Advanced Attribute Options page, for Name ID Format to send to SP select urn:oasis:names:tc:SAML:2.0:nameid-format:persistent. For IDP Attribute Name or Literal Value, select SAML_SUBJECT, as shown in Figure 4.
Figure 5. Advanced Attribute Options for SAML_SUBJECT
In the Attribute Mapping section line 2 as shown in Figure 4, for the application attribute https://aws.amazon.com/SAML/Attributes/Role, select Advanced.
On the Advanced Attribute Options page, for Name Format, select urn:oasis:names:tc:SAML:2.0:attrname-format:uri, as shown in Figure 6.
Figure 6. Advanced Attribute Options for https://aws.amazon.com/SAML/Attributes/Role
In the Attribute Mapping section line 2 as shown in Figure 4, select As Literal.
For IDP Attribute Name or Literal Value, format the role and provider ARNs (which are not yet created on the AWS side) in the following format. Be sure to replace the placeholders with your own values. Make a note of the role name and SAML provider name, as you will be using these exact names to create an IAM role and an IAM provider on the AWS side.
In the Attribute Mapping section line 3 as shown in Figure 4, for the application attribute https://aws.amazon.com/SAML/Attributes/RoleSessionName, enter Email (Work).
In the Attribute Mapping section as shown in Figure 4, to create line 5, choose Add a new attribute in the lower left.
In the newly added Attribute Mapping section line 5 as shown in Figure 4, add the SourceIdentity.
For Application Attribute, enter: https://aws.amazon.com/SAML/Attributes/SourceIdentity
For Identity Bridge Attribute or Literal Value, enter: SAML_SUBJECT
Choose Continue to Next Step in the lower right.
For Group Access, add your existing PingOne Directory Group to this application.
Review your setup configuration, as shown in Figure 7, and choose Finish.
Figure 7. Review mappings
Configure the SourceIdentity attribute with OneLogin integration
For the OneLogin SAML integration with AWS, you use the Amazon Web Services Multi Account application and configure an optional attribute to map as the SourceIdentity. You do this portion of the configuration in the OneLogin administrative console.
This procedure assumes that you already have a previously configured AWS and OneLogin integration. For information about how to configure the OneLogin application for AWS authentication and authorization, see the OneLogin KB article Configure SAML for Amazon Web Services (AWS) with Multiple Accounts and Roles.
After the OneLogin Multi Account application and AWS are correctly configured for SAML login, you can further customize the application to pass the SourceIdentity parameter upon login.
To change OneLogin configuration to add SourceIdentity attribute
In the OneLogin administrative console, in the Amazon Web Services Multi Account application, on the app administration page, navigate to Parameters, as shown in Figure 8.
Figure 8. OneLogin AWS Multi Account Application Configuration Parameters
To add a parameter, choose the + (plus) icon to the right of Value.
As shown in Figure 9, for Field Name enter https://aws.amazon.com/SAML/Attributes/SourceIdentity, select Include in SAML assertion, then choose Save.
Figure 9. OneLogin AWS Multi Account Application add new field
In the Edit Field page, select the default value you want to use for SourceIdentity. For the example in this blog post, for Value, select Email, then choose Save, as shown in Figure 10.
Figure 10. OneLogin AWS Multi Account Application map new field to email
After you’ve completed this procedure, review the final mapping details, as shown in Figure 11, to confirm that you see the additional parameter that will be passed into AWS through the SAML assertion.
Figure 11. OneLogin AWS Multi Account Application final mapping details
Configuring AWS IAM role trust policy
Now that the IdP configuration is complete, you can enable your AWS accounts to use SourceIdentity by modifying the IAM role trust policy.
For the workforce identity or application to be able to define their source identity when they assume IAM roles, you must first grant them permission for the sts:SetSourceIdentity action, as illustrated in the sample policy document below. This will permit the workforce identity or application to set the SourceIdentity themselves without any need for manual intervention.
To modify an AWS IAM role trust policy
Log in to the AWS Management Console for your account as a user with privileges to configure an IdP, typically an administrator.
Navigate to the AWS IAM service.
For trusted identity, choose SAML 2.0 federation.
From the SAML Provider drop down menu, select the IAM provider you created previously.
Modify the role trust policy and add the SetSourceIdentity action.
Sample policy document
This is a sample policy document attached to a role you assume when you log in to Account1 from the Okta dashboard. Edit your Account1/Role1 trust policy document and add sts:AssumeRoleWithSAML and sts:setSourceIdentity to the Action section.
Notes: The SetSourceIdentity action has to be allowed in the trust policy for assumeRole to work when the IdP is set up to pass SourceIdentity in the assertion. Future version of the sign-in URL may contain a Region code. When this occurs, you will need to modify the URL appropriately.
Policy statement
The following are examples of how the line “Federated”: “arn:aws:iam::<AccountId>:saml-provider/<IdP>” should look, based on the different IdPs specified in this post:
The following is a sample access control policy document in Account2 for Role2 that allows you to switchRole from Account1. Edit the control policy and add sts:AssumeRole and sts:SetSourceIdentity in the Action section.
Validate that the CloudTrail log entries for Account1 contain the Active Directory mapped SourceIdentity.
Use the Switch Role feature to switch to a second account Account2 (444455556666), using a role named Role2.
Create a new Amazon S3 bucket in Account2.
To summarize what you’ve done so far, you have:
Configured your corporate directory to pass a unique attribute to AWS as the source identity.
Configured a role that will persist the SourceIdentity attribute in AWS STS, which an employee will use to federate into your account.
Configured an Amazon S3 bucket that user will access.
Now you’ll observe in CloudTrail the SourceIdentity attribute that will be associated with every IAM action.
To see the SourceIdentity attribute in CloudTrail
From the your preferred IdP dashboard, select the AWS tile to log into the AWS console. The example in Figure 12 shows the Okta dashboard.
Figure 12. Login to AWS from IdP dashboard
Choose the AWS icon, which will take you to the AWS Management Console. Notice how the user has assumed the role you created earlier.
To test the SourceIdentity action, you will create a new Amazon S3 bucket.
Amazon S3 bucket names are globally unique, and the namespace is shared by all AWS accounts, so you will need to create a unique bucket name in your account. For this example, we used a bucket named DOC-EXAMPLE-BUCKET1 to validate CloudTrail log entries containing the SourceIdentity attribute.
Log into an account Account1 (111122223333) using a role named Role1.
Next, create a new Amazon S3 bucket in Account1, and validate that the Account1 CloudTrail logs entries contain the SourceIdentity attribute.
Create an Amazon S3 bucket called DOC-EXAMPLE-BUCKET1, as shown in Figure 13.
Figure 13. Create S3 bucket
In the AWS Management Console go to CloudTrail and check the log entry for bucket creation event, as shown in Figure 14.
Switch to Account2 (444455556666) using assume role, and switch to Account2/assumeRoleSourceIdentity.
Create a new Amazon S3 bucket in Account2 and validate that the Account2 CloudTrail log entries contain the SourceIdentity attribute, as shown in Figure 15.
Figure 15 – Switch role to assumeRoleSourceIdentity
Create a new Amazon S3 bucket in account2 called DOC-EXAMPLE-BUCKET2, as shown in Figure 16.
Figure 16 – Create DOC-EXAMPLE-BUCKET2 bucket while logged into account2 using assumeRoleSourceIdentity
Check the CloudTrail logs for account2 (444455556666) to see if the original SourceIdentity is logged, as shown in Figure 17.
Figure 17 – CloudTrail log entry for the above action
CloudTrail entry showing original SourceIdentity after assuming a role
You logged into Account1/Role1 and switched to Account2/Role2. All the user activities performed in AWS using the Assume Role were also logged with the original user’s sourceIdentity attribute. This makes it simple to trace user activity in CloudTrail.
Conclusion
Now that you have configured your SourceIdentity, you have made it easier for the security team of your organization to use CloudTrail logs to investigate and identify the originating identity of a user. In this post, you learned how to configure the AWS STSSourceIdentity attribute for three different popular IdPs, as well as how to configure each IdP using SAML and their optional attributes. We also provided sample control policy documents outlining how to configure the SourceIdentity for each provider. Additionally, we provide a sample policy for setting the SourceIdentity when switching roles. Lastly, the post walks through how the source identity will show in CloudTrail logs, and provides logs from two accounts to demonstrate the continuance of the source identity attribute. You can now test this capability yourself in your own environment, validate activity in your CloudTrail logs, and determine which user performed a specific action while using the assumeRole functionality.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
In the AWS Security Profile series, I interview some of the humans who work in Amazon Web Services (AWS) Security and help keep our customers safe and secure. This interview is with Philip Winstanley, a security engineer and AWS Guardian. The Guardians program identifies and develops security experts within engineering teams across AWS, enabling these teams to use Amazon Security more effectively. Through the empowerment of these security-minded Amazonians called “Guardians,” we foster a culture of informed security ownership throughout the development lifecycle.
How long have you been at AWS, and what do you do in your current role?
I’ve been with AWS for just over three years now. I joined in Dublin, Ireland, and I’ve since transferred back to the UK, back to my home city of Manchester. I’m a security engineer on the service team for AWS Managed Services (AMS). We support customer workloads in the cloud and help customers manage them, optimize them, and keep them safe and secure.
How did you get started in the world of security?
I was a software developer for many years, and in building software I discovered that security is an integral part of delivering safe and secure solutions to my customers. That really sparked my interest in the security space, and I started researching and learning about all the different types of attacks that were out there, and learning about organized crime. That led me to work with the UK’s National Crime Agency, where I became a special officer, and to the United Kingdom Royal Airforce, where I worked in the cyber defense team. I managed to merge my technical knowledge with my law enforcement and military knowledge, and then bring them all together as the security engineer that I am today.
What are you currently working on that you’re excited about?
I have the joy of working with full-spectrum security, which is everything from protecting our environments to detecting risks within our environments to responding to those risks. But the bulk of my work is in helping our service teams build safe and secure software. Sometimes we call that AppSec (application security), sometimes we call it secure development. As part of that, I work with a group of volunteers and specialists within engineering teams that we call Guardians. They are our security specialists embedded within AWS service teams. These are people who champion security and make sure that everything we build meets a high security bar, which often goes beyond what we’re asked to do by compliance or regulation. We take it that extra mile. As Guardians, we push our development teams to continually raise the bar on security, privacy, compliance, and the confidentiality of customer data.
What are the most important aspects of being a Guardian?
A Guardian is there to help teams do the right thing when it comes to security—to contextualize knowledge of their team’s business and technology and help them identify areas and opportunities to improve security. Guardians will often think outside the box. They will come at things from a security point of view, not just a development point of view. But they do it within the context of what our customers need. Guardians are always looking around corners; they’re looking at what’s coming next. They’re looking at the risks that are out there, looking at the way environments are evolving, and trying to build in protections now for issues that will come down the line. Guardians are there to help our service teams anticipate and protect against future risks.
How have you as a Guardian improved the quality of security outcomes for customers?
Many of our customers are moving to the cloud, some for the first time, and they have high standards around data sovereignty, around the privacy of the data they manage. In addition to helping service teams meet the security bar, Guardians seek to understand our customers’ security and privacy requirements. As a result, our teams’ Guardians inform the development of features that not only meet our security bar, but also help our customers meet their security, privacy, and compliance requirements.
How have you helped develop security experts within your team?
I have the joy of working with security experts from many different fields. Inside Amazon, we have a huge community of security expertise, touching every single domain of security. What we try to do is cross-pollinate; we teach each other about our own areas of expertise. I focus on application security and work very closely with my colleagues who work in threat intelligence and incident response. We all work together and collaborate to raise the bar for each of us, sharing our knowledge, our skills, our expertise. We do this through training that we build, we do it through knowledge-sharing sessions where we get together and talk about security issues, we do it through being jointly introspective about the work that we’ve done. We will even do reviews of each other’s work and bar raise, adding our own specialist knowledge and expertise to that of our colleagues.
What advice would you give to customers who are considering their own Guardians program?
Security culture is something that comes from within an organization. It’s also something that’s best when it’s done from the ground up. You can’t just tell people to be secure, you have to find people who are passionate about security and empower them. Give them permission to put that passion into their work and give them the opportunity to learn from security training and experts. What you’ll see, if you have people with that passion for security, is that they’ll bring that enthusiasm into the work from the start. They’ll already care about security and want to do more of it.
You’re a self-described “disruptive anti-CISO.” What does that mean?
I wrote a piece on LinkedIn about what it really is, but I’ll give a shorter answer. The world of information security is not new—it’s been around for 20, 30 years, so all the thinking around security comes from a world of on-premises infrastructure. It’s from a time before the cloud even existed and unfortunately, a lot of the security thinking out there is still borne of that age. When we’re in a world of hyper-scaled environments, where we’re dealing with millions of resources, millions of endpoints, we can’t use that traditional thinking anymore. We can’t just lock everything in a box and make sure no one’s got access to it. Quite the opposite, we need to enable innovations, we need to let the business drive that creativity and produce solutions, which means security needs to be an enabler of creativity, not a blocker. I have a firm belief that security plays a part in delivering solutions, in helping solutions land, and making sure that they succeed. Security is not and should never be a gatekeeper to success. More often than not in industries, that was the position that security took. I believe in the opposite—security should enable business. I take that thinking and use it to help AWS customers succeed, through sharing our experience and knowledge with them to keep them safe and secure in the cloud.
What’s the thing you’re most proud of in your career?
When I was at the National Crime Agency, I worked in the dark web threat intelligence unit and some of my work was to combat child exploitation and human trafficking. The work I did there was some of the most rewarding I’ve ever done, and I’m incredibly proud of what we achieved. But it wasn’t just within that agency, it was partnering with other organizations, police forces around the world, and cloud providers such as AWS that combat exploitation and help move vulnerable children into safety. Working to protect victims of crime, especially the most vulnerable, helped me build a customer-centric view to security, ensuring we always think about our end customers and their customers. It’s all about people; we are here to protect and defend families and real lives, not just 1’s and 0’s.
If you had to pick an industry outside of security, what would you want to do?
I have always loved space and would adore working in the space sector. I’m fascinated by all of the renewed space exploration that’s happening at the moment, be it through Blue Origin or Space X or any of these other people out there doing it. If I could have my time again, or even if I could pivot now in my career, I would go and be a space man. I don’t need to be an astronaut, but I would want to contribute to the success of these missions and see humanity go out into the stars.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Location data is subjected to heavy scrutiny by security experts. Knowing the current position of a person, vehicle, or asset can provide industries with many benefits, whether to understand where a current delivery is, how many people are inside a venue, or to optimize routing for a fleet of vehicles. This blog post explains how Amazon Web Services (AWS) helps keep location data secured in transit and at rest, and how you can leverage additional security features to help keep information safe and compliant.
The General Data Protection Regulation (GDPR) defines personal data as “any information relating to an identified or identifiable natural person (…) such as a name, an identification number, location data, an online identifier or to one or more factors specific to the physical, physiological, genetic, mental, economic, cultural or social identity of that natural person.” Also, many companies wish to improve transparency to users, making it explicit when a particular application wants to not only track their position and data, but also to share that information with other apps and websites. Your organization needs to adapt to these changes quickly to maintain a secure stance in a competitive environment.
On June 1, 2021, AWS made Amazon Location Service generally available to customers. With Amazon Location, you can build applications that provide maps and points of interest, convert street addresses into geographic coordinates, calculate routes, track resources, and invoke actions based on location. The service enables you to access location data with developer tools and to move your applications to production faster with monitoring and management capabilities.
In this blog post, we will show you the features that Amazon Location provides out of the box to keep your data safe, along with best practices that you can follow to reach the level of security that your organization strives to accomplish.
Data control and data rights
Amazon Location relies on global trusted providers Esri and HERE Technologies to provide high-quality location data to customers. Features like maps, places, and routes are provided by these AWS Partners so solutions can have data that is not only accurate but constantly updated.
AWS anonymizes and encrypts location data at rest and during its transmission to partner systems. In parallel, third parties cannot sell your data or use it for advertising purposes, following our service terms. This helps you shield sensitive information, protect user privacy, and reduce organizational compliance risks. To learn more, see the Amazon Location Data Security and Control documentation.
Integrations
Operationalizing location-based solutions can be daunting. It’s not just necessary to build the solution, but also to integrate it with the rest of your applications that are built in AWS. Amazon Location facilitates this process from a security perspective by integrating with services that expedite the development process, enhancing the security aspects of the solution.
Encryption
Amazon Location uses AWS owned keys by default to automatically encrypt personally identifiable data. AWS owned keys are a collection of AWS Key Management Service (AWS KMS) keys that an AWS service owns and manages for use in multiple AWS accounts. Although AWS owned keys are not in your AWS account, Amazon Location can use the associated AWS owned keys to protect the resources in your account.
If customers choose to use their own keys, they can benefit from AWS KMS to store their own encryption keys and use them to add a second layer of encryption to geofencing and tracking data.
Authentication and authorization
Amazon Location also integrates with AWS Identity and Access Management (IAM), so that you can use its identity-based policies to specify allowed or denied actions and resources, as well as the conditions under which actions are allowed or denied on Amazon Location. Also, for actions that require unauthenticated access, you can use unauthenticated IAM roles.
As an extension to IAM, Amazon Cognito can be an option if you need to integrate your solution with a front-end client that authenticates users with its own process. In this case, you can use Cognito to handle the authentication, authorization, and user management for you. You can use Cognito unauthenticated identity pools with Amazon Location as a way for applications to retrieve temporary, scoped-down AWS credentials. To learn more about setting up Cognito with Amazon Location, see the blog post Add a map to your webpage with Amazon Location Service.
Limit the scope of your unauthenticated roles to a domain
When you are building an application that allows users to perform actions such as retrieving map tiles, searching for points of interest, updating device positions, and calculating routes without needing them to be authenticated, you can make use of unauthenticated roles.
When using unauthenticated roles to access Amazon Location resources, you can add an extra condition to limit resource access to an HTTP referer that you specify in the policy. The aws:referer request context value is provided by the caller in an HTTP header, and it is included in a web browser request.
The following is an example of a policy that allows access to a Map resource by using the aws:referer condition, but only if the request comes from the domain example.com.
Encrypt tracker and geofence information using customer managed keys with AWS KMS
When you create your tracker and geofence collection resources, you have the option to use a symmetric customer managed key to add a second layer of encryption to geofencing and tracking data. Because you have full control of this key, you can establish and maintain your own IAM policies, manage key rotation, and schedule keys for deletion.
After you create your resources with customer managed keys, the geometry of your geofences and all positions associated to a tracked device will have two layers of encryption. In the next sections, you will see how to create a key and use it to encrypt your own data.
Create an AWS KMS symmetric key
First, you need to create a key policy that will limit the AWS KMS key to allow access to principals authorized to use Amazon Location and to principals authorized to manage the key. For more information about specifying permissions in a policy, see the AWS KMS Developer Guide.
To create the key policy
Create a JSON policy file by using the following policy as a reference. This key policy allows Amazon Location to grant access to your KMS key only when it is called from your AWS account. This works by combining the kms:ViaService and kms:CallerAccount conditions. In the following policy, replace us-west-2 with your AWS Region of choice, and the kms:CallerAccount value with your AWS account ID. Adjust the KMS Key Administrators statement to reflect your actual key administrators’ principals, including yourself. For details on how to use the Principal element, see the AWS JSON policy elements documentation.
Tip: AWS CLI will consider the Region you defined as the default during the configuration steps, but you can override this configuration by adding –region<your region> at the end of each command line in the following command. Also, make sure that your user has the appropriate permissions to perform those actions.
To create the symmetric key
Now, create a symmetric key on AWS KMS by running the create-key command and passing the policy file that you created in the previous step.
Create an Amazon Location tracker and geofence collection resources
To create an Amazon Location tracker resource that uses AWS KMS for a second layer of encryption, run the following command, passing the key ID from the previous step.
By following these steps, you have added a second layer of encryption to your geofence collection and tracker.
Data retention best practices
Trackers and geofence collections are stored and never leave your AWS account without your permission, but they have different lifecycles on Amazon Location.
Trackers store the positions of devices and assets that are tracked in a longitude/latitude format. These positions are stored for 30 days by the service before being automatically deleted. If needed for historical purposes, you can transfer this data to another data storage layer and apply the proper security measures based on the shared responsibility model.
Geofence collections store the geometries you provide until you explicitly choose to delete them, so you can use encryption with AWS managed keys or your own keys to keep them for as long as needed.
Asset tracking and location storage best practices
After a tracker is created, you can start sending location updates by using the Amazon Location front-end SDKs or by calling the BatchUpdateDevicePosition API. In both cases, at a minimum, you need to provide the latitude and longitude, the time when the device was in that position, and a device-unique identifier that represents the asset being tracked.
Protecting device IDs
This device ID can be any string of your choice, so you should apply measures to prevent certain IDs from being used. Some examples of what to avoid include:
First and last names
Facility names
Documents, such as driver’s licenses or social security numbers
Emails
Addresses
Telephone numbers
Latitude and longitude precision
Latitude and longitude coordinates convey precision in degrees, presented as decimals, with each decimal place representing a different measure of distance (when measured at the equator).
Amazon Location supports up to six decimal places of precision (0.000001), which is equal to approximately 11 cm or 4.4 inches at the equator. You can limit the number of decimal places in the latitude and longitude pair that is sent to the tracker based on the precision required, increasing the location range and providing extra privacy to users.
Figure 1 shows a latitude and longitude pair, with the level of detail associated to decimals places.
Figure 1: Geolocation decimal precision details
Position filtering
Amazon Location introduced position filtering as an option to trackers that enables cost reduction and reduces jitter from inaccurate device location updates.
DistanceBased filtering ignores location updates wherein devices have moved less than 30 meters (98.4 ft).
TimeBased filtering evaluates every location update against linked geofence collections, but not every location update is stored. If your update frequency is more often than 30 seconds, then only one update per 30 seconds is stored for each unique device ID.
AccuracyBased filtering ignores location updates if the distance moved was less than the measured accuracy provided by the device.
By using filtering options, you can reduce the number of location updates that are sent and stored, thus reducing the level of location detail provided and increasing the level of privacy.
Logging and monitoring
Amazon Location integrates with AWS services that provide the observability needed to help you comply with your organization’s security standards.
To record all actions that were taken by users, roles, or AWS services that access Amazon Location, consider using AWS CloudTrail. CloudTrail provides information on who is accessing your resources, detailing the account ID, principal ID, source IP address, timestamp, and more. Moreover, Amazon CloudWatch helps you collect and analyze metrics related to your Amazon Location resources. CloudWatch also allows you to create alarms based on pre-defined thresholds of call counts. These alarms can create notifications through Amazon Simple Notification Service (Amazon SNS) to automatically alert teams responsible for investigating abnormalities.
Conclusion
At AWS, security is our top priority. Here, security and compliance is a shared responsibility between AWS and the customer, where AWS is responsible for protecting the infrastructure that runs all of the services offered in the AWS Cloud. The customer assumes the responsibility to perform all of the necessary security configurations to the solutions they are building on top of our infrastructure.
In this blog post, you’ve learned the controls and guardrails that Amazon Location provides out of the box to help provide data privacy and data protection to our customers. You also learned about the other mechanisms you can use to enhance your security posture.
Start building your own secure geolocation solutions by following the Amazon Location Developer Guide and learn more about how the service handles security by reading the security topics in the guide.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this blog post, start a new thread on Amazon Location Service forum or contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.