Tag Archives: storage

Optimizing vector search using Amazon S3 Vectors and Amazon OpenSearch Service

Post Syndicated from Sohaib Katariwala original https://aws.amazon.com/blogs/big-data/optimizing-vector-search-using-amazon-s3-vectors-and-amazon-opensearch-service/

NOTE: As of July 15, the Amazon S3 Vectors Integration with Amazon OpenSearch Service is in preview release and is subject to change.

The way we store and search through data is evolving rapidly with the advancement of vector embeddings and similarity search capabilities. Vector search has become essential for modern applications such as generative AI and agentic AI, but managing vector data at scale presents significant challenges. Organizations often struggle with the trade-offs between latency, cost, and accuracy when storing and searching through millions or billions of vector embeddings. Traditional solutions either require substantial infrastructure management or come with prohibitive costs as data volumes grow.

We now have a public preview of two integrations between Amazon Simple Storage Service (Amazon S3) Vectors and Amazon OpenSearch Service that give you more flexibility in how you store and search vector embeddings:

  1. Cost-optimized vector storage: OpenSearch Service managed clusters using service-managed S3 Vectors for cost-optimized vector storage. This integration will support OpenSearch workloads that are willing to trade off higher latency for ultra-low cost and still want to use advanced OpenSearch capabilities (such as hybrid search, advanced filtering, geo filtering, and so on).
  2. One-click export from S3 Vectors: One-click export from an S3 vector index to OpenSearch Serverless collections for high-performance vector search. Customers who build natively on S3 Vectors will benefit from being able to use OpenSearch for faster query performance.

By using these integrations, you can optimize cost, latency, and accuracy by intelligently distributing your vector workloads by keeping infrequent queried vectors in S3 Vectors and using OpenSearch for your most time-sensitive operations that require advanced search capabilities such as hybrid search and aggregations. Further, OpenSearch performance tuning capabilities (that is, quantization, k-nearest neighbor (knn) algorithms, and method-specific parameters) help to improve the performance with little compromise of cost or accuracy.

In this post, we walk through this seamless integration, providing you with flexible options for vector search implementation. You’ll learn how to use the new S3 Vectors engine type in OpenSearch Service managed clusters for cost-optimized vector storage and how to use one-click export from S3 Vectors to OpenSearch Serverless collections for high-performance scenarios requiring sustained queries with latency as low as 10ms. By the end of this post, you’ll understand how to choose and implement the right integration pattern based on your specific requirements for performance, cost, and scale.

Service overview

Amazon S3 Vectors is the first cloud object store with native support to store and query vectors with sub-second search capabilities, requiring no infrastructure management. It combines the simplicity, durability, availability, and cost-effectiveness of Amazon S3 with native vector search functionality, so you can store and query vector embeddings directly in S3. Amazon OpenSearch Service provides two complementary deployment options for vector workloads: Managed Clusters and Serverless Collections. Both harness Amazon OpenSearch’s powerful vector search and retrieval capabilities, though each excels in different scenarios. For OpenSearch users, the integration between S3 Vectors and Amazon OpenSearch Service offers unprecedented flexibility in optimizing your vector search architecture. Whether you need ultra-fast query performance for real-time applications or cost-effective storage for large-scale vector datasets, this integration lets you choose the approach that best fits your specific use case.

Understanding Vector Storage Options

OpenSearch Service provides multiple options for storing and searching vector embeddings, each optimized for different use cases. The Lucene engine, which is OpenSearch’s native search library, implements the Hierarchical Navigable Small World (HNSW) method, offering efficient filtering capabilities and strong integration with OpenSearch’s core functionality. For workloads requiring additional optimization options, the Faiss engine (Facebook AI Similarity Search) provides implementations of both HNSW and IVF (Inverted File Index) methods, along with vector compression capabilities. HNSW creates a hierarchical graph structure of connections between vectors, enabling efficient navigation during search, while IVF organizes vectors into clusters and searches only relevant subsets during query time. With the introduction of the S3 engine type, you now have a cost-effective option that uses Amazon S3’s durability and scalability while maintaining sub-second query performance. With this variety of options, you can choose the most suitable approach based on your specific requirements for performance, cost, and accuracy. For instance, if your application requires sub-50 ms query responses with efficient filtering, Faiss’s HNSW implementation is the best choice. Alternatively, if you need to optimize storage costs while maintaining reasonable performance, the new S3 engine type would be more appropriate.

Solution overview

In this post, we explore two primary integration patterns:

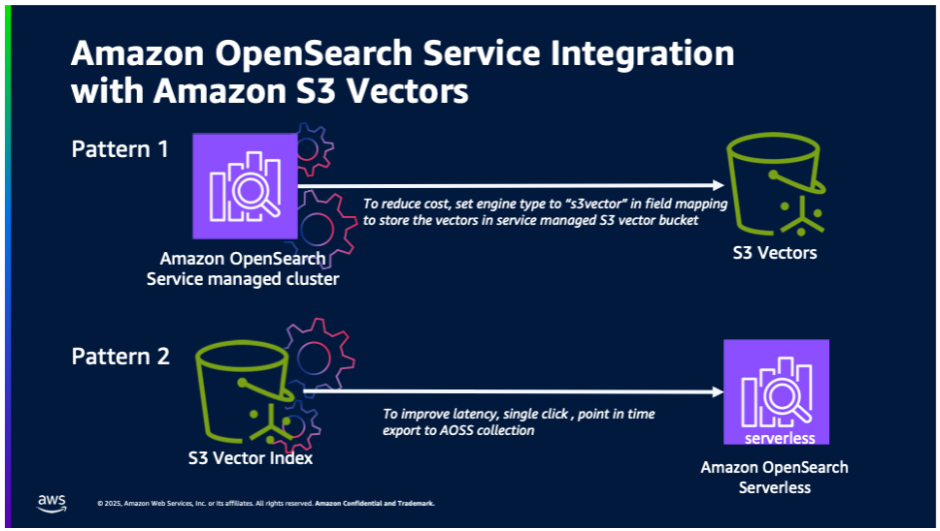
OpenSearch Service managed clusters using service-managed S3 Vectors for cost-optimized vector storage.

For customers already using OpenSearch Service domains who want to optimize costs while maintaining sub-second query performance, the new Amazon S3 engine type offers a compelling solution. OpenSearch Service automatically manages vector storage in Amazon S3, data retrieval, and cache optimization, eliminating operational overhead.

One-click export from an S3 vector index to OpenSearch Serverless collections for high-performance vector search.

For use cases requiring faster query performance, you can migrate your vector data from an S3 vector index to an OpenSearch Serverless collection. This approach is ideal for applications that require real-time response times and gives you the benefits that come with Amazon OpenSearch Serverless, including advanced query capabilities and filters, automatic scaling and high availability, and no administration. The export process automatically handles schema mapping, vector data transfer, index optimization, and connection configuration.

The following illustration shows the two integration patterns between Amazon OpenSearch Service and S3 Vectors.
Prerequisites

Before you begin, make sure you have:

  • An AWS account
  • Access to Amazon S3 and Amazon OpenSearch Service
  • An OpenSearch Service domain (for the first integration pattern)
  • Vector data stored in S3 Vectors (for the second integration pattern)

Integration pattern 1: OpenSearch Service managed cluster using S3 Vectors

To implement this pattern:

  1. Create an OpenSearch Service Domain using OR1 instances on OpenSearch version 2.19.
    1. While creating the OpenSearch Service domain, choose the Enable S3 Vectors as an engine option in the Advanced features section.
  2. Sign in to OpenSearch Dashboards and open Dev tools. Then create your knn index and specify s3vector as the engine.
PUT my-first-s3vector-index
{
  "settings": {
    "index": {
      "knn": true
    }
  },
  "mappings": {
    "properties": {
        "my_vector1": {
          "type": "knn_vector",
          "dimension": 2,
          "space_type": "l2",
          "method": {
            "engine": "s3vector"
          }
        },
        "price": {
          "type": "float"
        }
    }
  }
} 
  1. Index your vectors using the Bulk API:
POST _bulk
{ "index": { "_index": "my-first-s3vector-index", "_id": "1" } }
{ "my_vector1": [2.5, 3.5], "price": 7.1 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "3" } }
{ "my_vector1": [3.5, 4.5], "price": 12.9 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "4" } }
{ "my_vector1": [5.5, 6.5], "price": 1.2 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "5" } }
{ "my_vector1": [4.5, 5.5], "price": 3.7 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "6" } }
{ "my_vector1": [1.5, 2.5], "price": 12.2 }
  1. Run a knn query as usual:
GET my-first-s3vector-index/_search
{
  "size": 2,
  "query": {
    "knn": {
      "my_vector1": {
        "vector": [2.5, 3.5],
        "k": 2
      }
    }
  }
}

The following animation demonstrates steps 2-4 above.
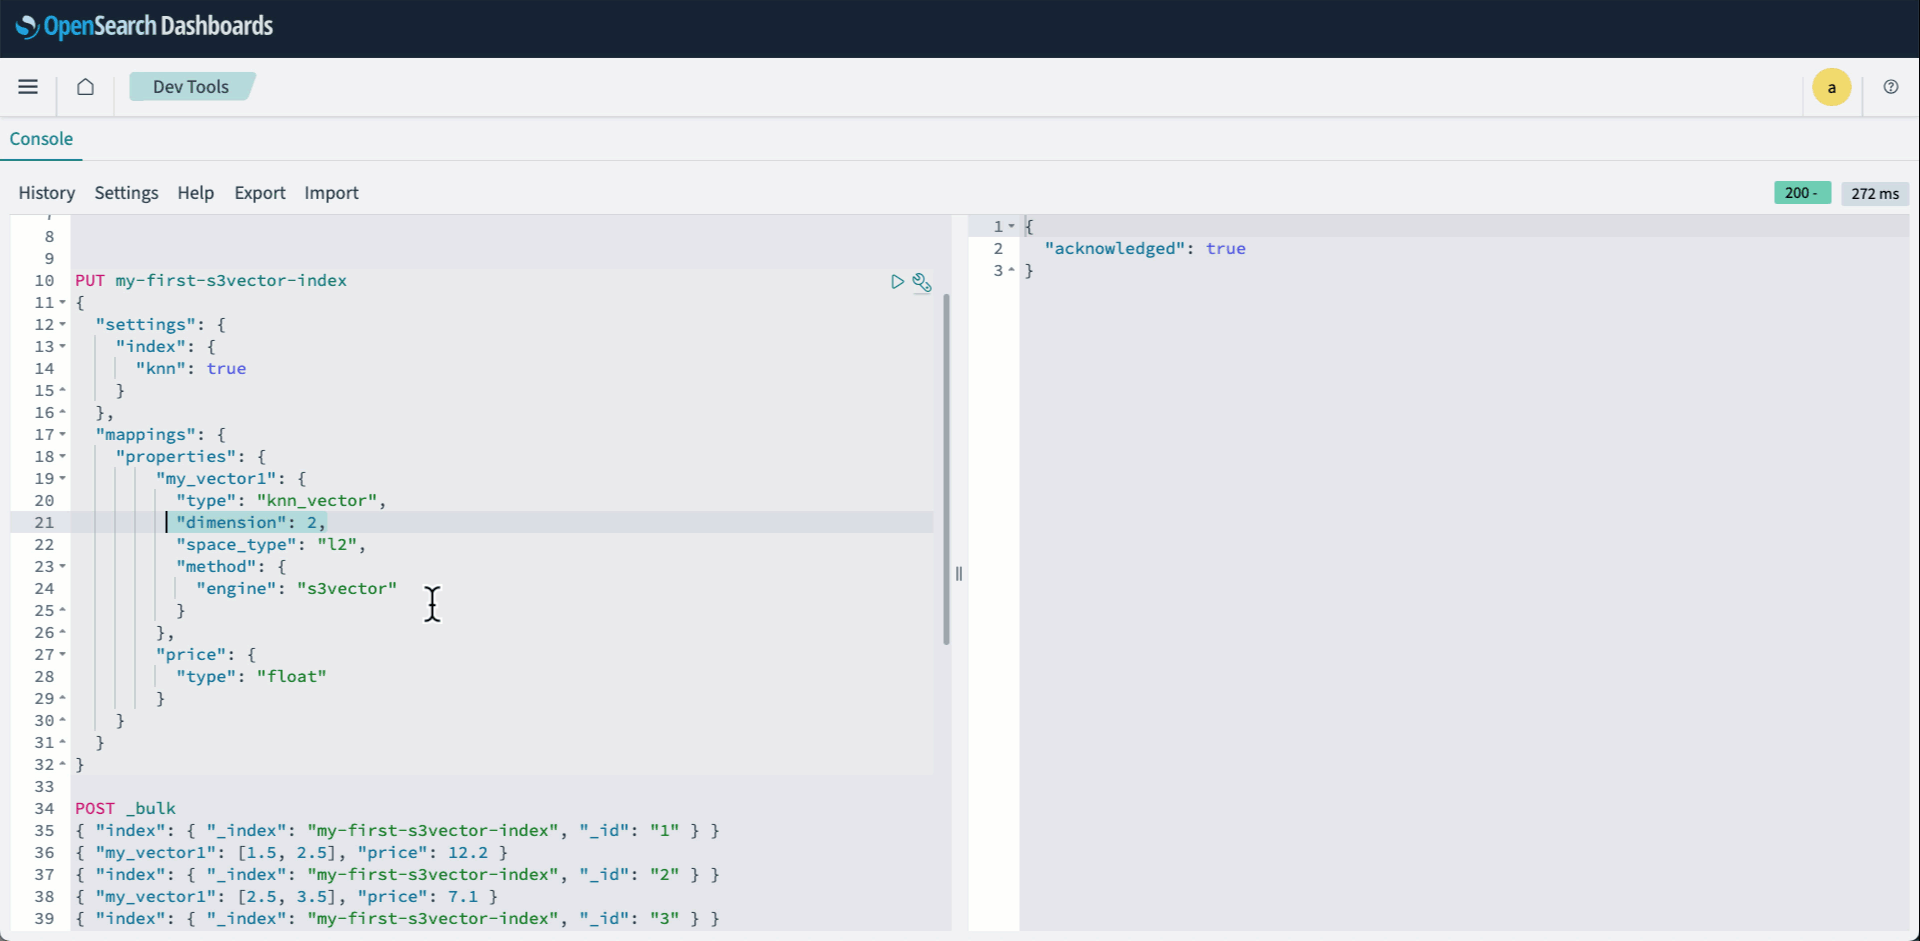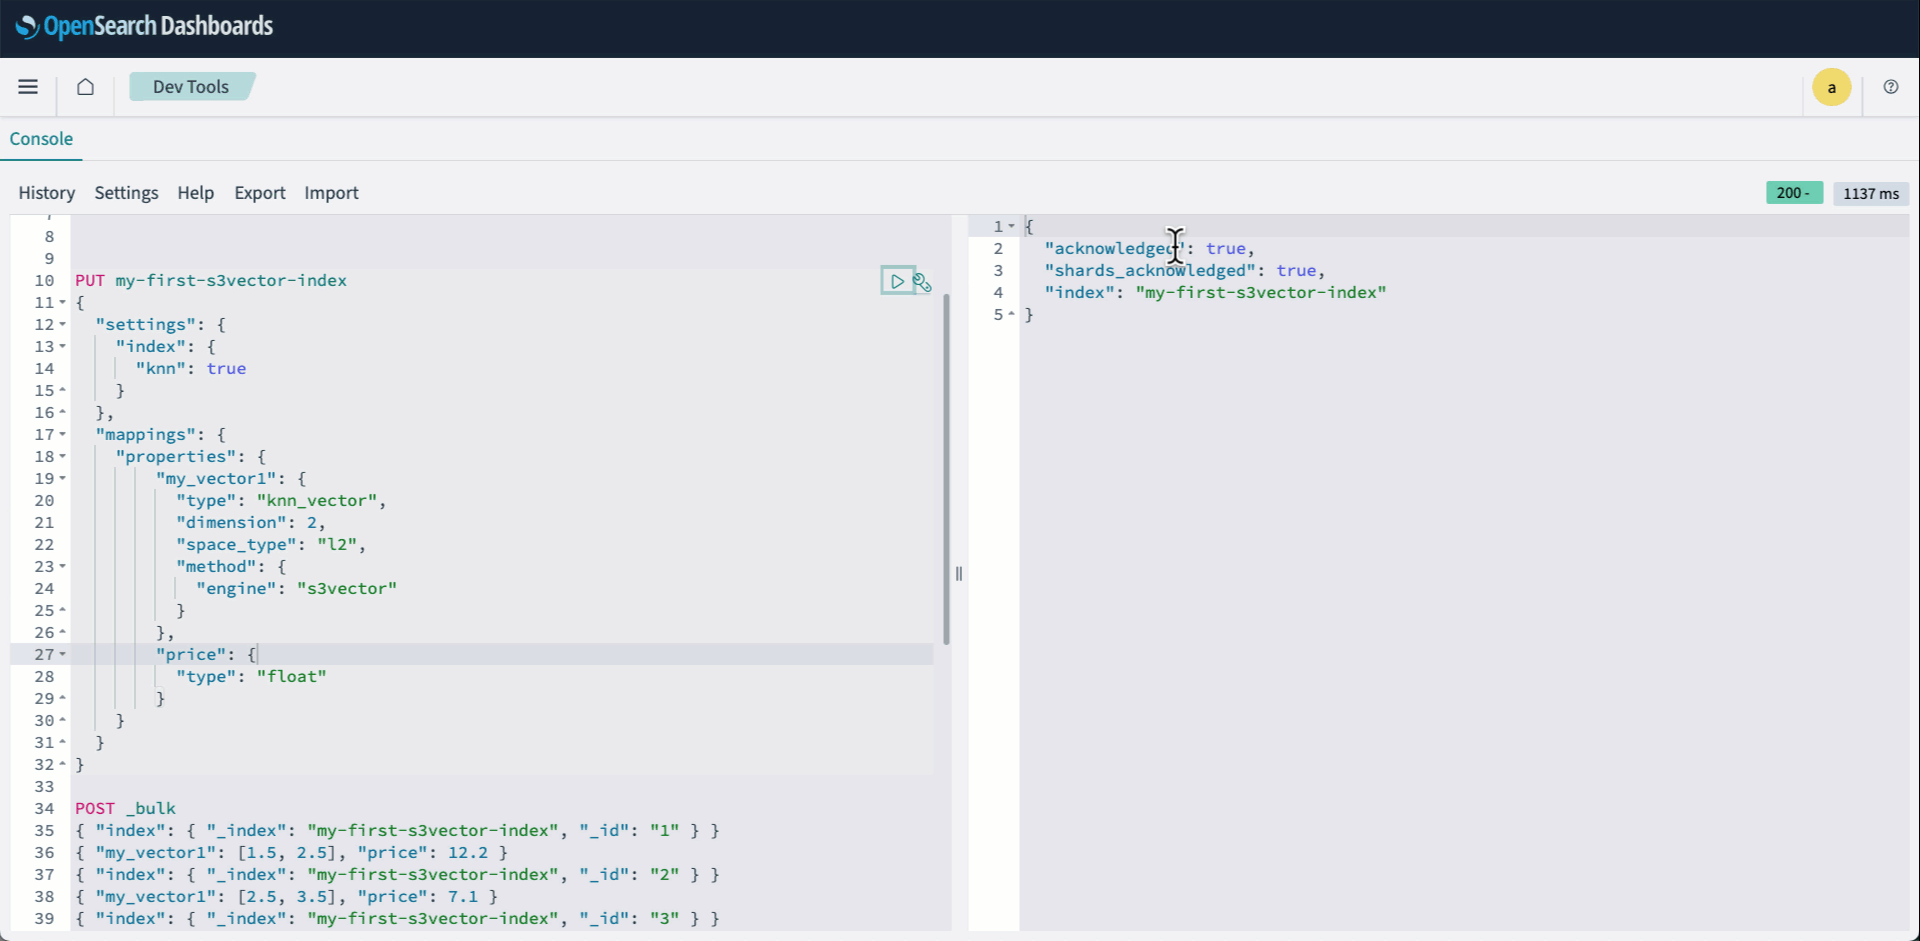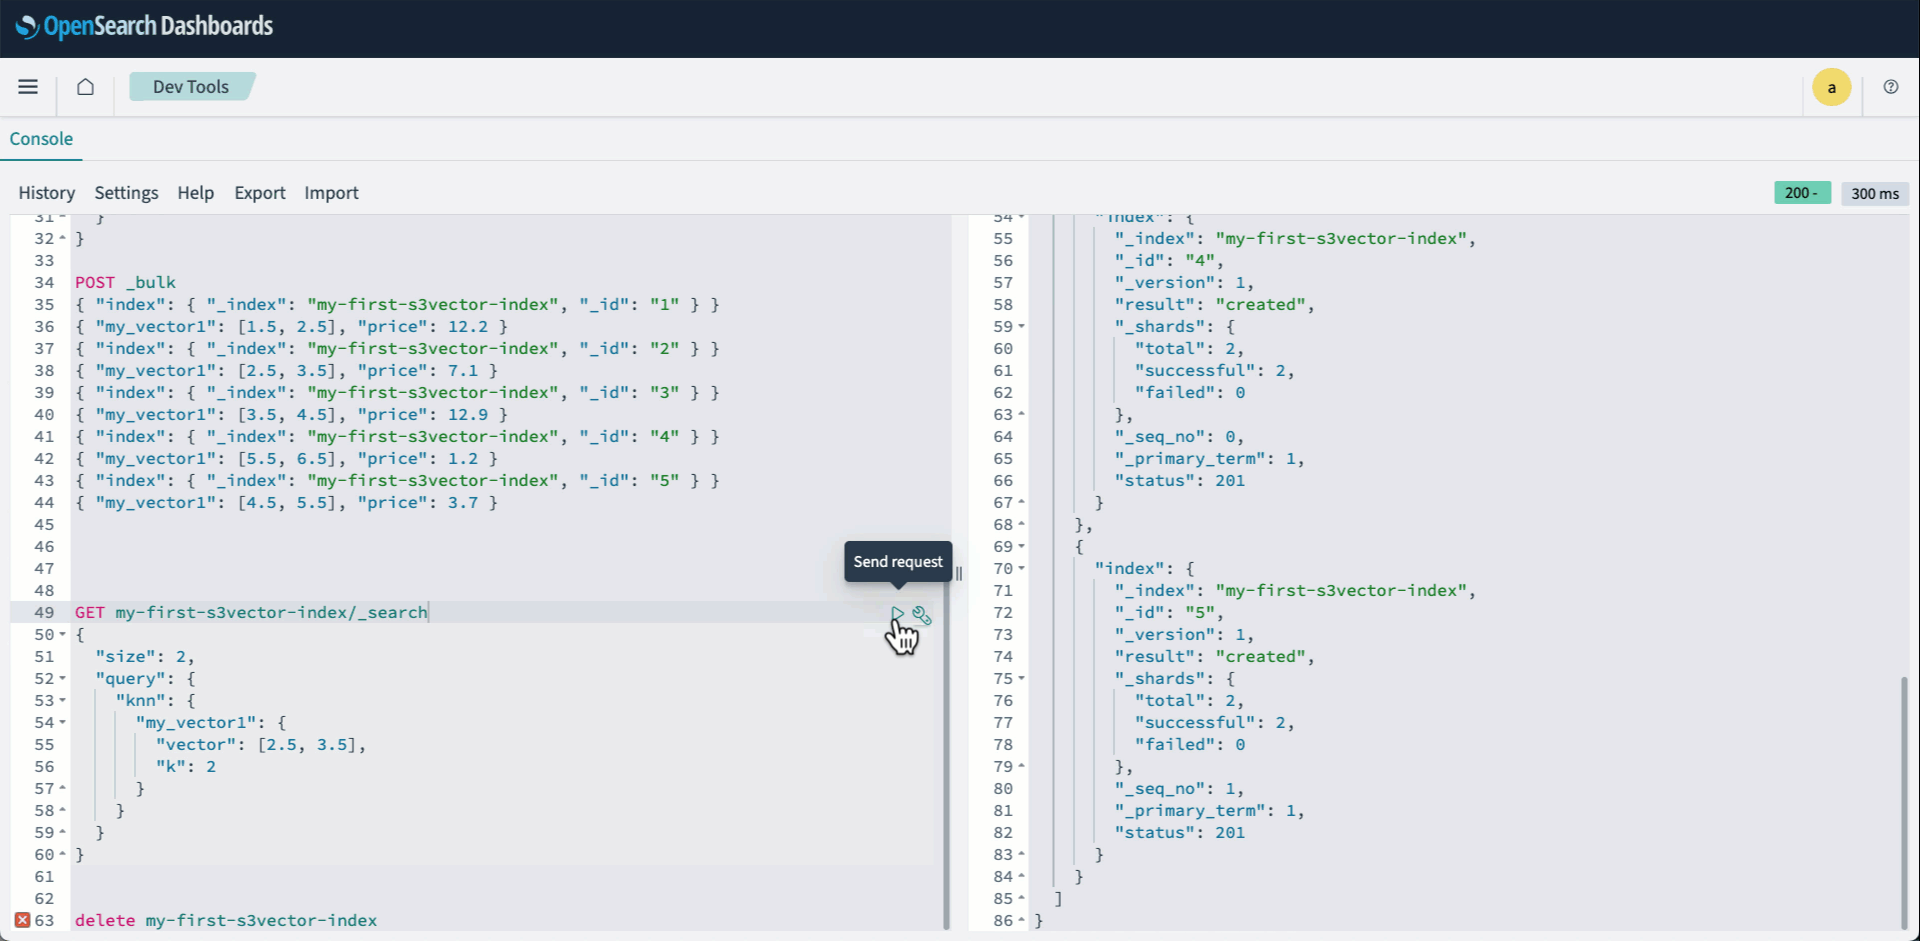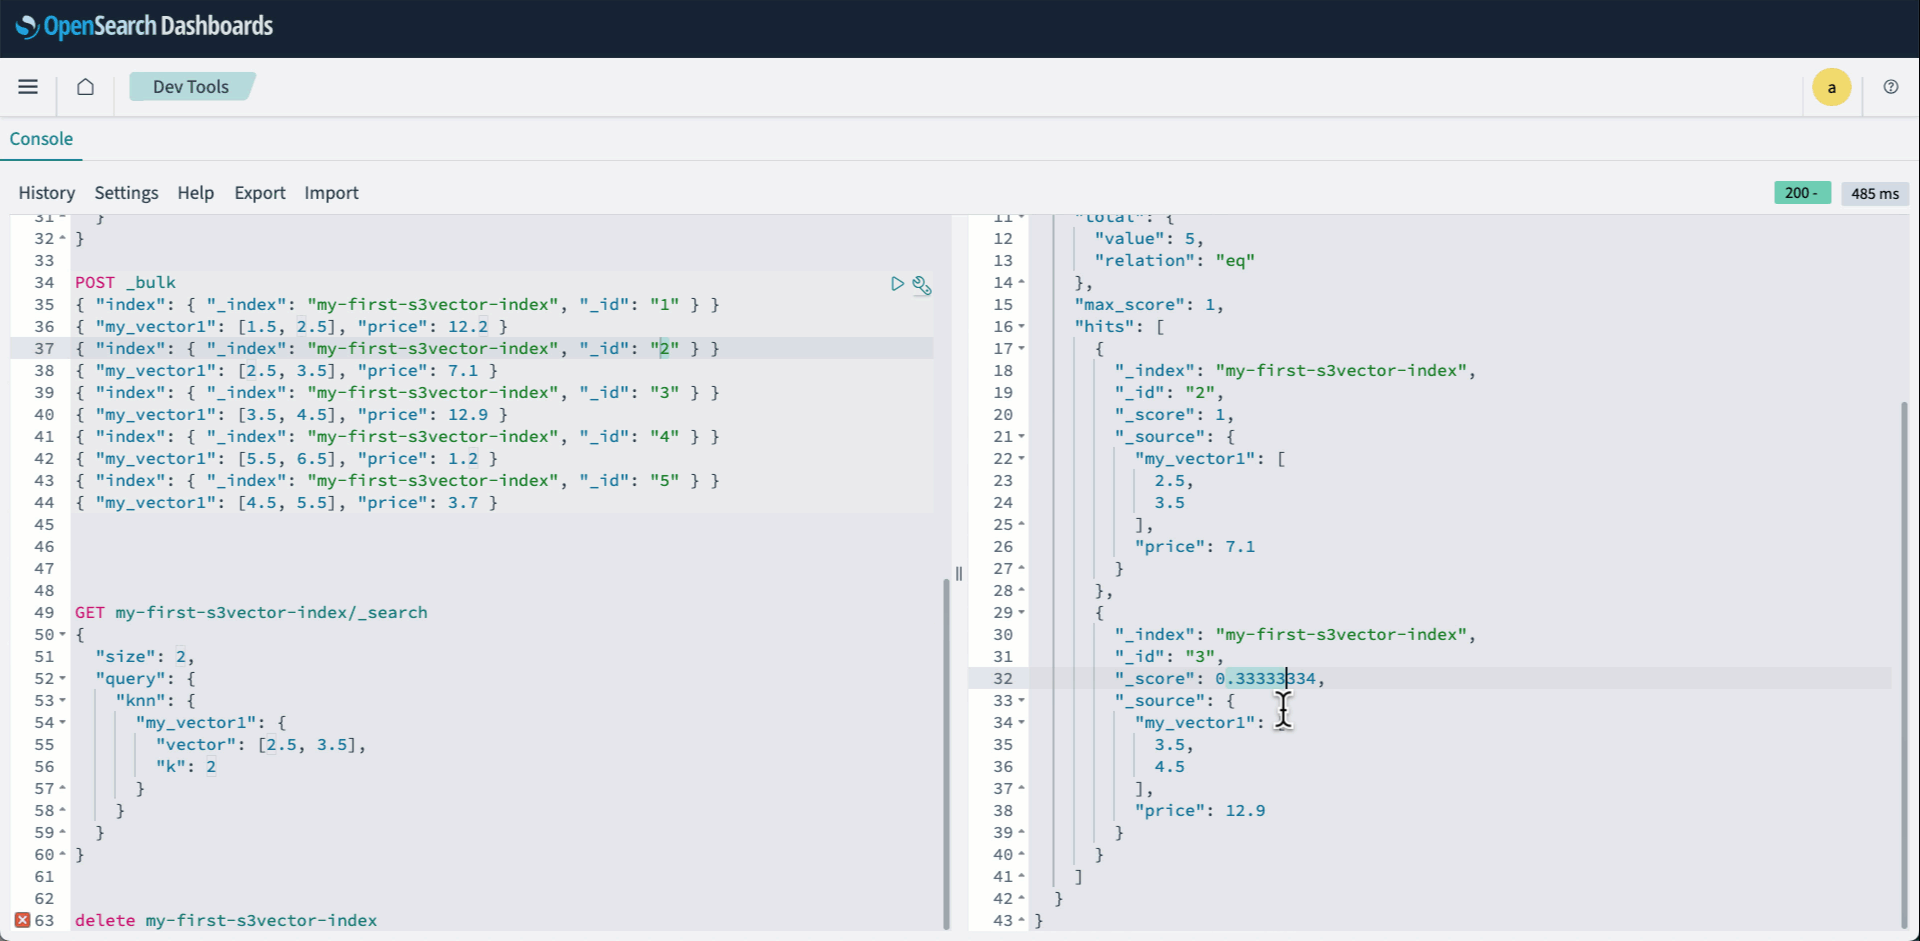
Integration pattern 2: Export S3 vector indexes to OpenSearch Serverless

To implement this pattern:

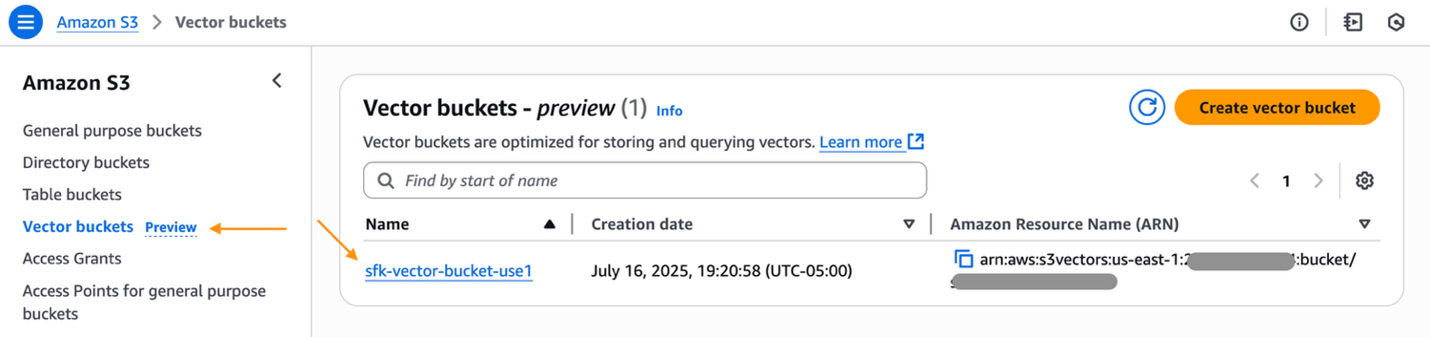
  1. Navigate to the AWS Management Console for Amazon S3 and select your S3 vector bucket.
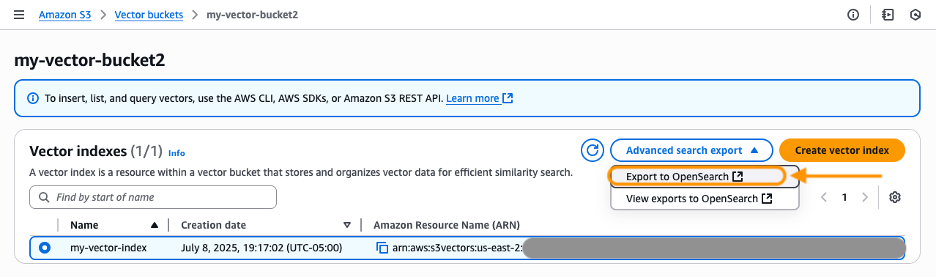
  1. Select a vector index that you want to export. Under Advanced search export, select Export to OpenSearch.
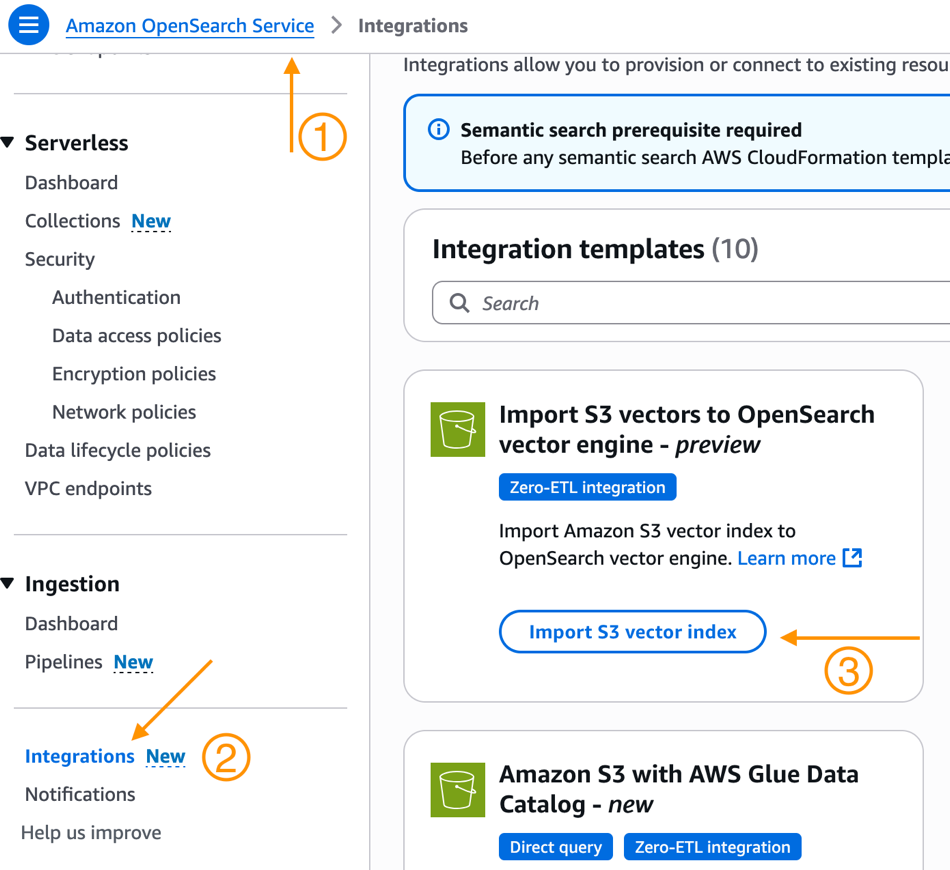
Alternatively, you can:

  1. Navigate to the OpenSearch Service console.
  2. Select Integrations from the navigation pane.
  3. Here you will see a new Integration Template to Import S3 vectors to OpenSearch vector engine – preview. Select Import S3 vector index.
  1. You will now be brought to the Amazon OpenSearch Service integration console with the Export S3 vector index to OpenSearch vector engine template pre-selected and pre-populated with your S3 vector index Amazon Resource Name (ARN). Select an existing role that has the necessary permissions or create a new service role.
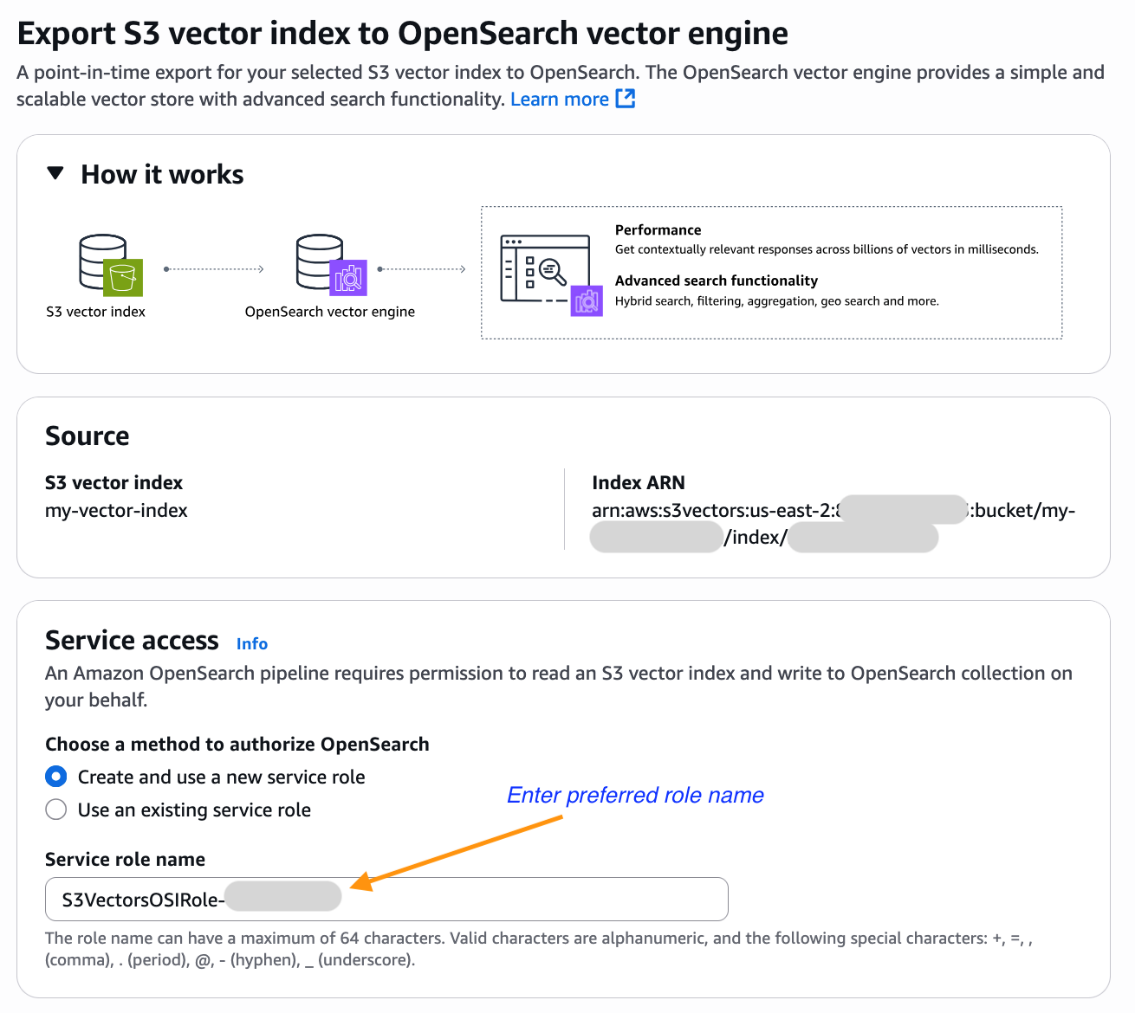
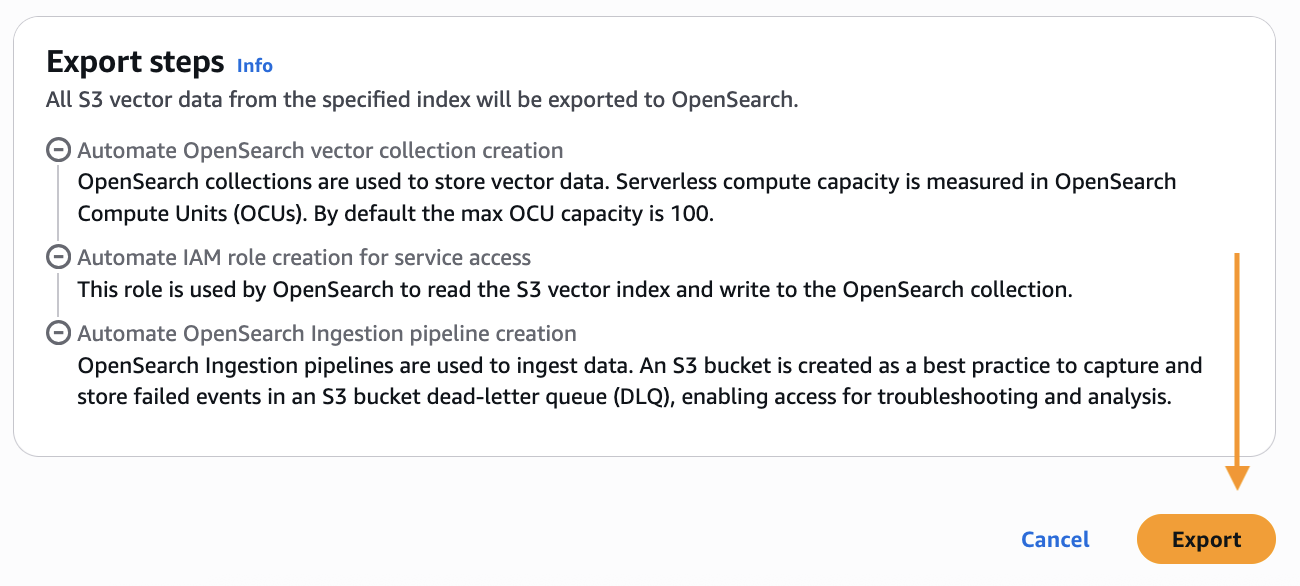
  1. Scroll down and choose Export to start the steps to create a new OpenSearch Serverless collection and copy data from your S3 vector index into an OpenSearch knn index.
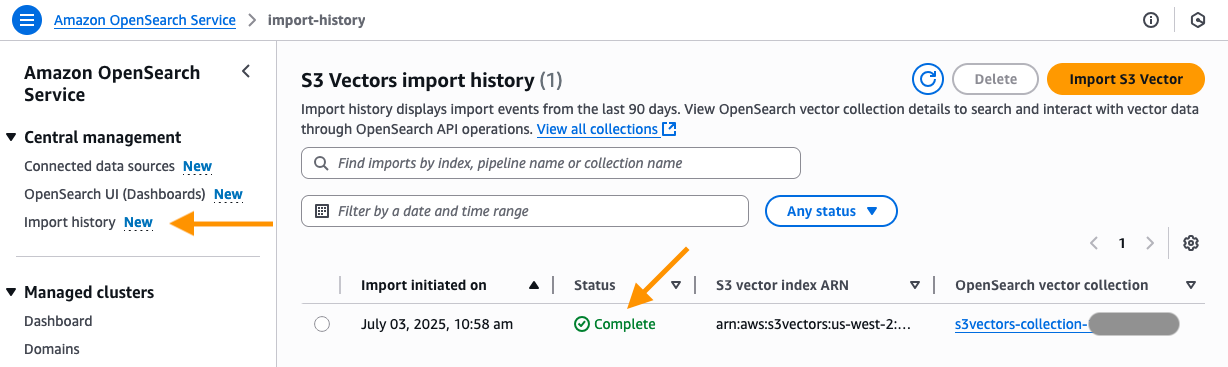
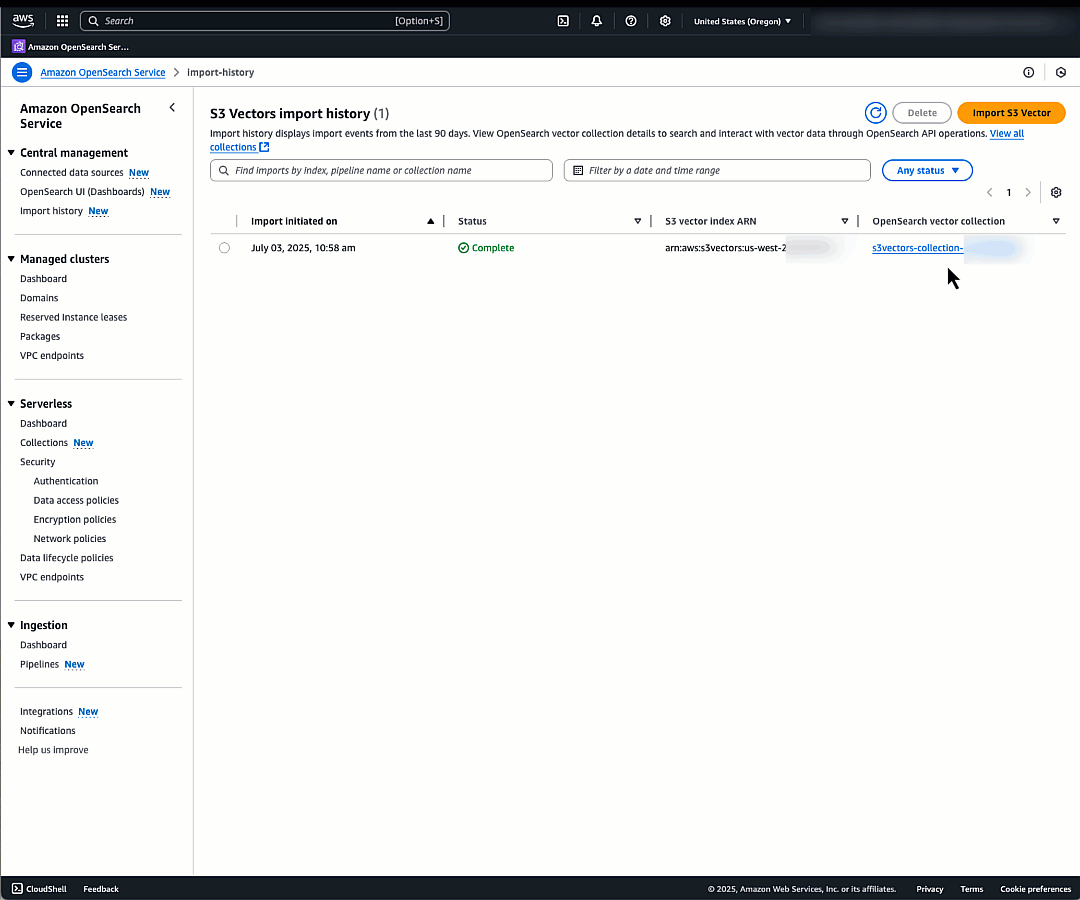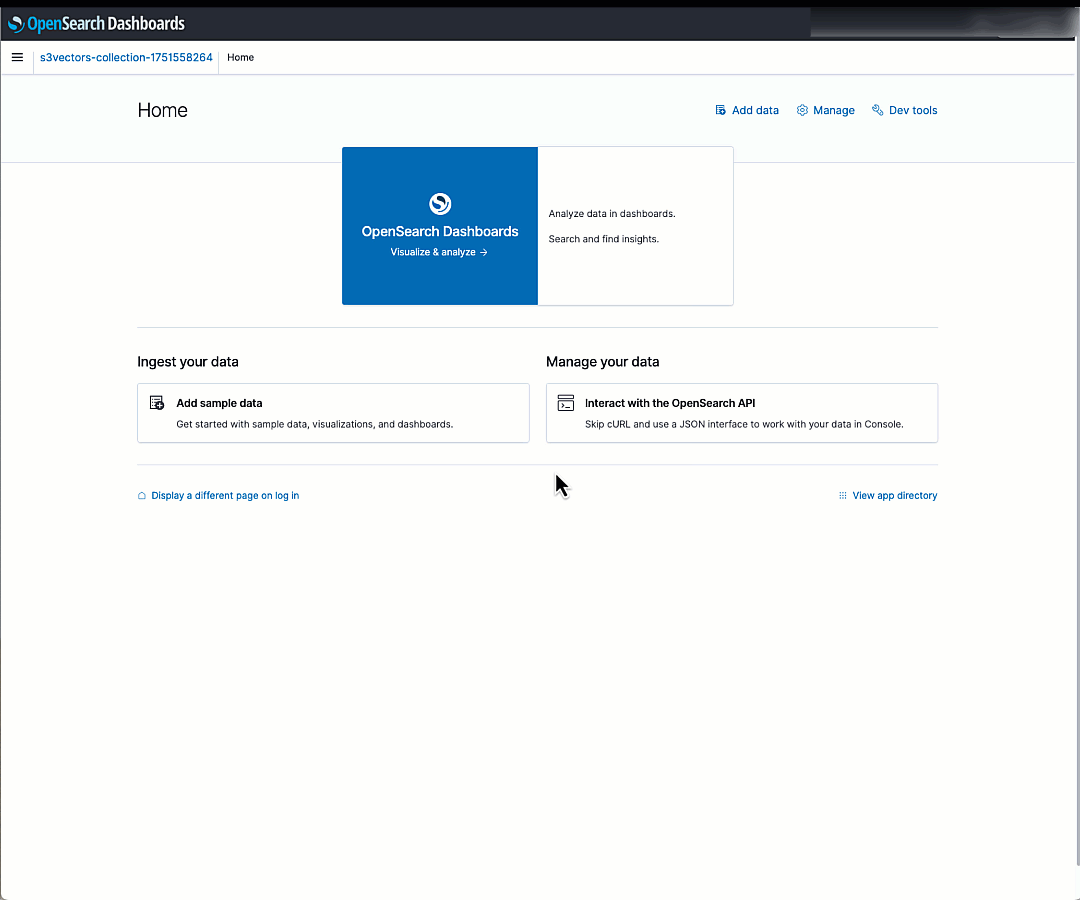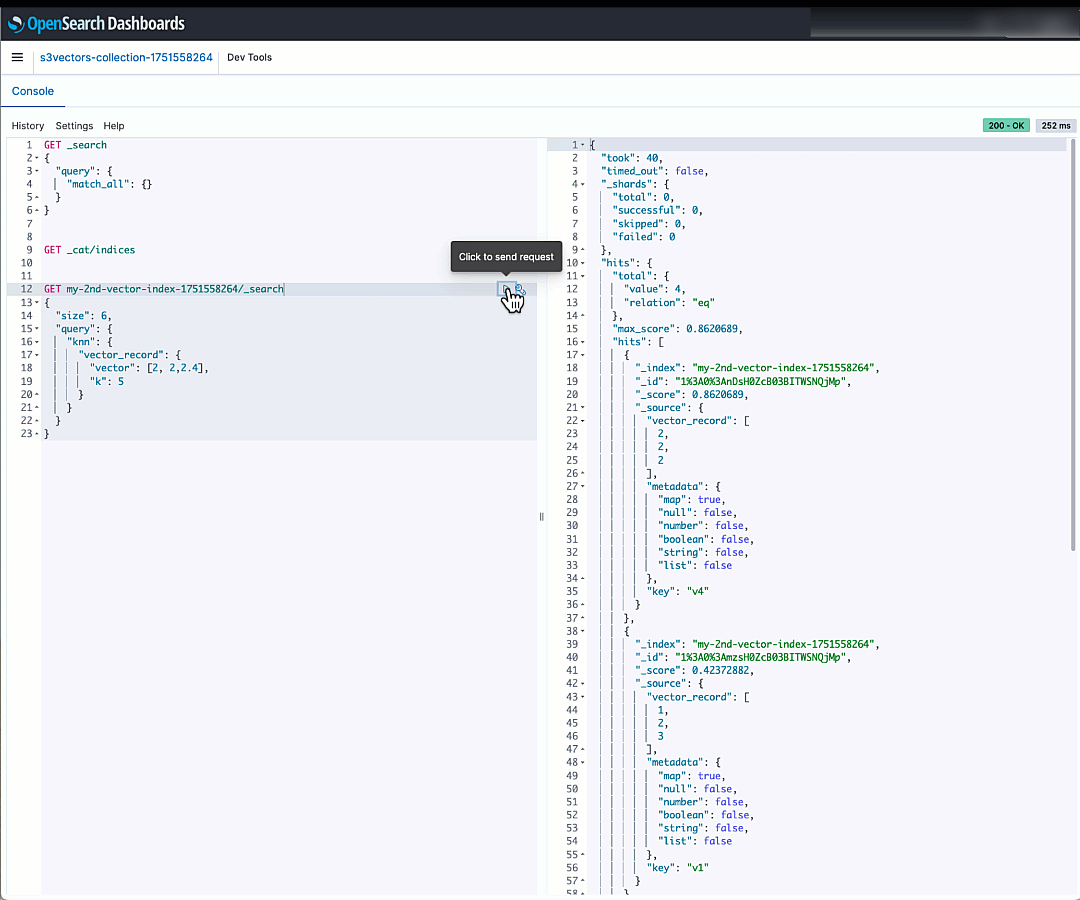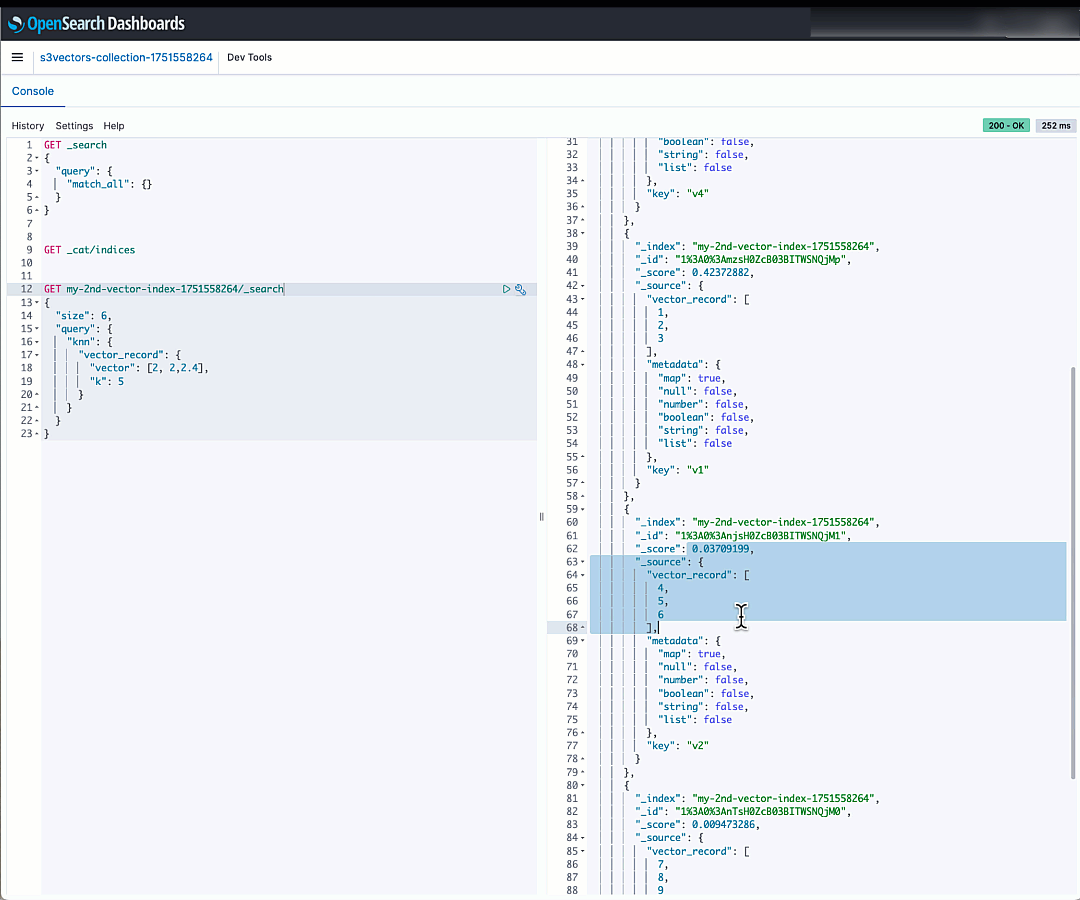
  1. You will now be taken to the Import history page in the OpenSearch Service console. Here you will see the new job that was created to migrate your S3 vector index into the OpenSearch serverless knn index. After the status changes from In Progress to Complete, you can connect to the new OpenSearch serverless collection and query your new OpenSearch knn index.
The following animation demonstrates how to connect to the new OpenSearch serverless collection and query your new OpenSearch knn index using Dev tools.
Cleanup

To avoid ongoing charges:

  1. For Pattern 1:
  1. For Pattern 2:
    • Delete the import task from the Import history section of the OpenSearch Service console. Deleting this task will remove both the OpenSearch vector collection and the OpenSearch Ingestion pipeline that was automatically created by the import task.

Conclusion

The innovative integration between Amazon S3 Vectors and Amazon OpenSearch Service marks a transformative milestone in vector search technology, offering unprecedented flexibility and cost-effectiveness for enterprises. This powerful combination delivers the best of both worlds: The renowned durability and cost efficiency of Amazon S3 merged seamlessly with the advanced AI search capabilities of OpenSearch. Organizations can now confidently scale their vector search solutions to billions of vectors while maintaining control over their latency, cost, and accuracy. Whether your priority is ultra-fast query performance with latency as low as 10ms through OpenSearch Service, or cost-optimized storage with impressive sub-second performance using S3 Vectors or implementing advanced search capabilities in OpenSearch, this integration provides the perfect solution for your specific needs. We encourage you to get started today by trying S3 Vectors engine in your OpenSearch managed clusters and testing the one-click export from S3 vector indexes to OpenSearch Serverless.

For more information, visit:


About the Authors

Sohaib Katariwala is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service based out of Chicago, IL. His interests are in all things data and analytics. More specifically he loves to help customers use AI in their data strategy to solve modern day challenges.
Mark Twomey is a Senior Solutions Architect at AWS focused on storage and data management. He enjoys working with customers to put their data in the right place, at the right time, for the right cost. Living in Ireland, Mark enjoys walking in the countryside, watching movies, and reading books.
Sorabh Hamirwasia is a senior software engineer at AWS working on the OpenSearch Project. His primary interest include building cost optimized and performant distributed systems.
Pallavi Priyadarshini is a Senior Engineering Manager at Amazon OpenSearch Service leading the development of high-performing and scalable technologies for search, security, releases, and dashboards.
Bobby Mohammed is a Principal Product Manager at AWS leading the Search, GenAI, and Agentic AI product initiatives. Previously, he worked on products across the full lifecycle of machine learning, including data, analytics, and ML features on SageMaker platform, deep learning training and inference products at Intel.
Quicksilver v2: evolution of a globally distributed key-value store (Part 2)

Post Syndicated from Marten van de Sanden original https://blog.cloudflare.com/quicksilver-v2-evolution-of-a-globally-distributed-key-value-store-part-2-of-2/

What is Quicksilver?

Cloudflare has servers in 330 cities spread across 125+ countries. All of these servers run Quicksilver, which is a key-value database that contains important configuration information for many of our services, and is queried for all requests that hit the Cloudflare network.

Because it is used while handling requests, Quicksilver is designed to be very fast; it currently responds to 90% of requests in less than 1 ms and 99.9% of requests in less than 7 ms. Most requests are only for a few keys, but some are for hundreds or even more keys.

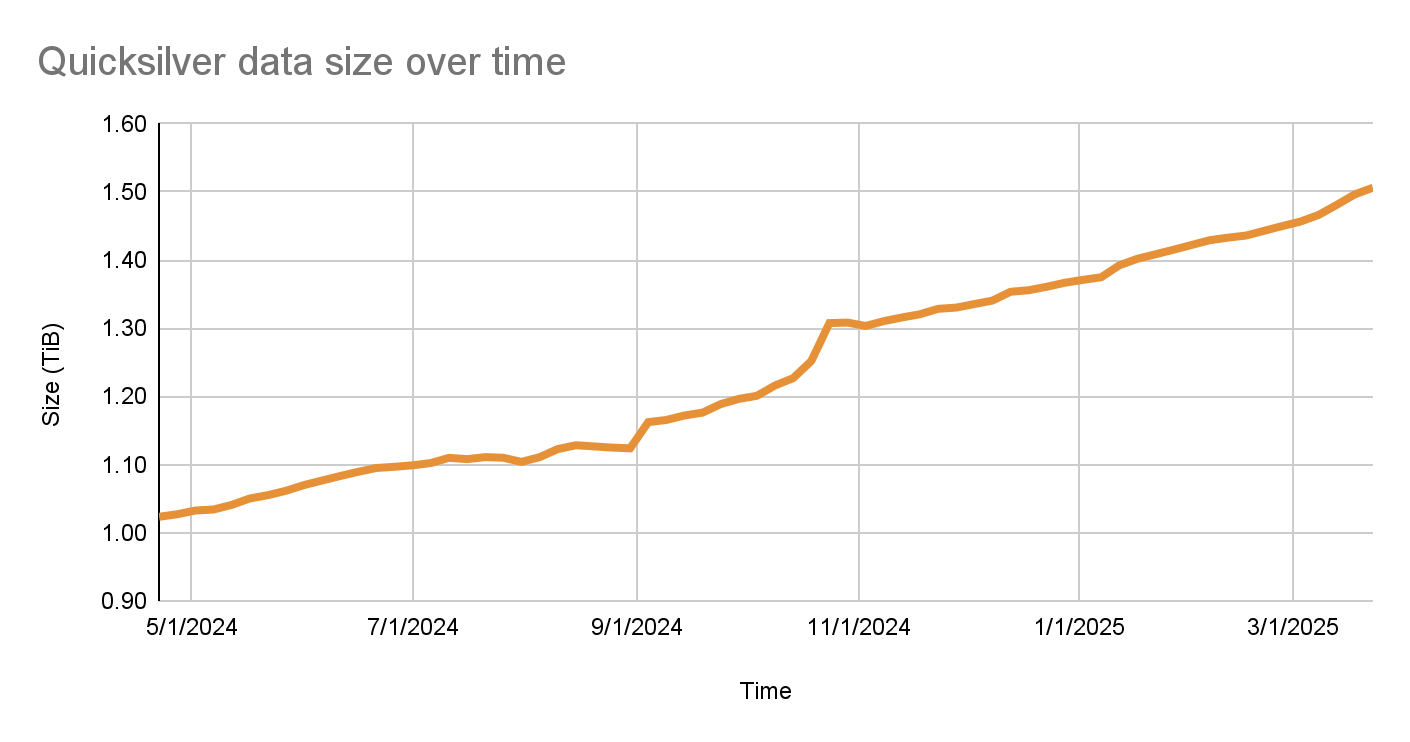
Quicksilver currently contains over five billion key-value pairs with a combined size of 1.6 TB, and it serves over three billion keys per second, worldwide. Keeping Quicksilver fast provides some unique challenges, given that our dataset is always growing, and new use cases are added regularly.

Quicksilver used to store all key-values on all servers everywhere, but there is obviously a limit to how much disk space can be used on every single server. For instance, the more disk space used by Quicksilver, the less disk space is left for content caching. Also, with each added server that contains a particular key-value, the cost of storing that key-value increases.

This is why disk space usage has been the main battle that the Quicksilver team has been waging over the past several years. A lot was done over the years, but we now think that we have finally created an architecture that will allow us to get ahead of the disk space limitations and finally make Quicksilver scale better.


The size of the Quicksilver database has grown by 50% to about 1.6 TB in the past year

What we talked about previously

Part one of the story explained how Quicksilver V1 stored all key-value pairs on each server all around the world. It was a very simple and fast design, it worked very well, and it was a great way to get started. But over time, it turned out to not scale well from a disk space perspective.

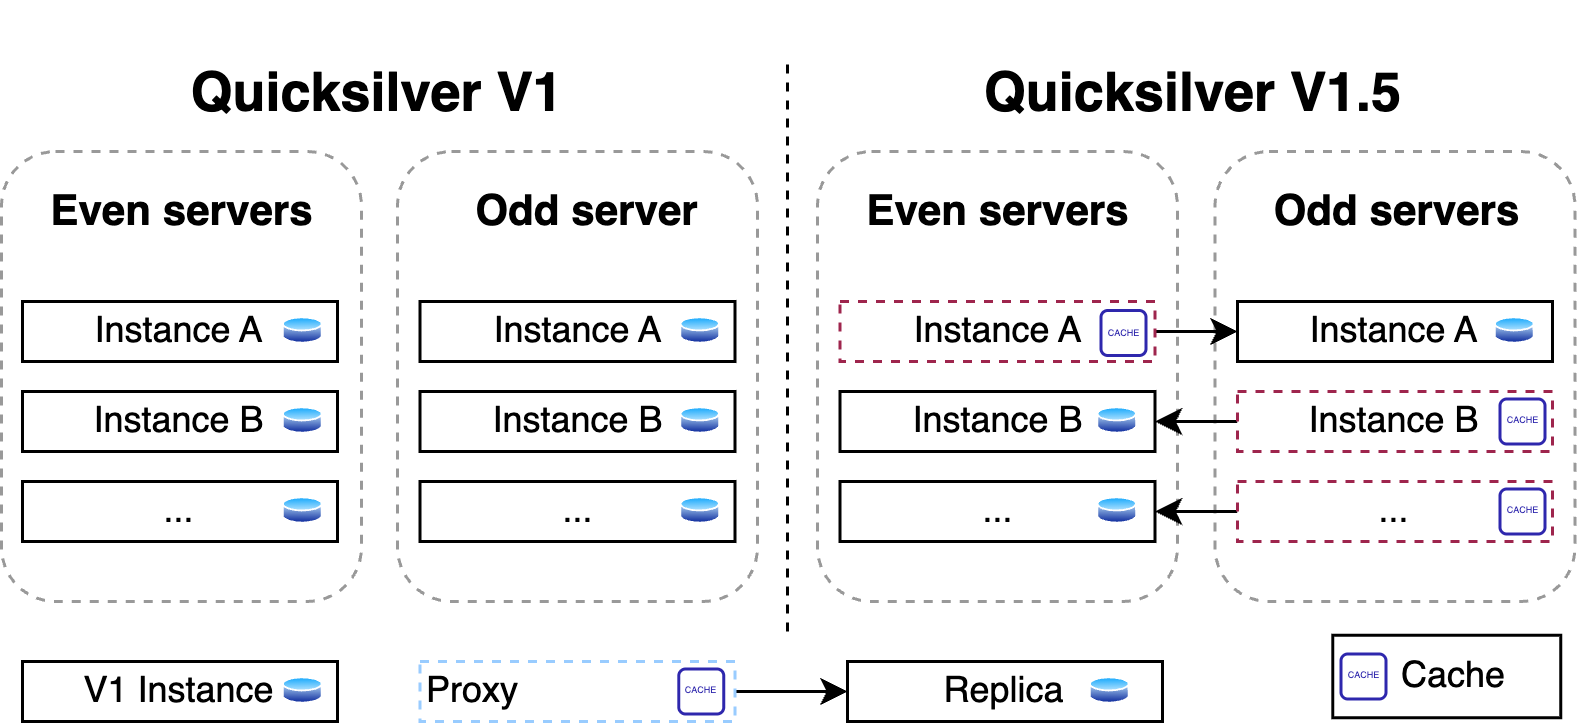
The problem was that disk space was running out so fast that there was not enough time to design and implement a fully scalable version of Quicksilver. Therefore, Quicksilver V1.5 was created first. It halved the disk space used on each server compared to V1.

For this, a new proxy mode was introduced for Quicksilver. In this mode, Quicksilver does not contain the full dataset anymore, but only contains a cache. All cache misses are looked up on another server that runs Quicksilver with a full dataset. Each server runs about ten separate instances of Quicksilver, and all have different databases with different sets of key-values. We call Quicksilver instances with the full data set replicas.

For Quicksilver V1.5, half of those instances on a particular server would run Quicksilver in proxy mode, and therefore would not have the full dataset anymore. The other half would run in replica mode. This worked well for a time, but it was not the final solution.


Building this intermediate solution had the added benefit of allowing the team to gain experience running an even more distributed version of Quicksilver.

The problem

There were a few reasons why Quicksilver V1.5 was not fully scalable.

First, the size of the separate instances were not very stable. The key-space is owned by the teams that use Quicksilver, not by the Quicksilver team, and the way those teams use Quicksilver changes frequently. Furthermore, while most instances grow in size over time, some instances have actually gotten smaller, such as when the use of Quicksilver is optimised by teams. The result of this is that the split of instances that was well-balanced at the start, quickly became unbalanced.

Second, the analyses that were done to estimate how much of the key space would need to be in cache on each server assumed that taking all keys that were accessed in a three-day period would represent a good enough cache. This assumption turned out to be wildly off. This analysis estimated that we needed about 20% of the key space in cache, which turned out to not be entirely accurate. Whereas most instances did have a good cache hit rate, with 20% or less of the key space in cache, some instances turned out to need a much higher percentage.

The main issue, however, was that reducing the disk space used by Quicksilver on our network by as much as 40% does not actually make it more scalable. The number of key-values that are stored in Quicksilver keeps growing. It only took about two years before disk space was running low again.

The solution


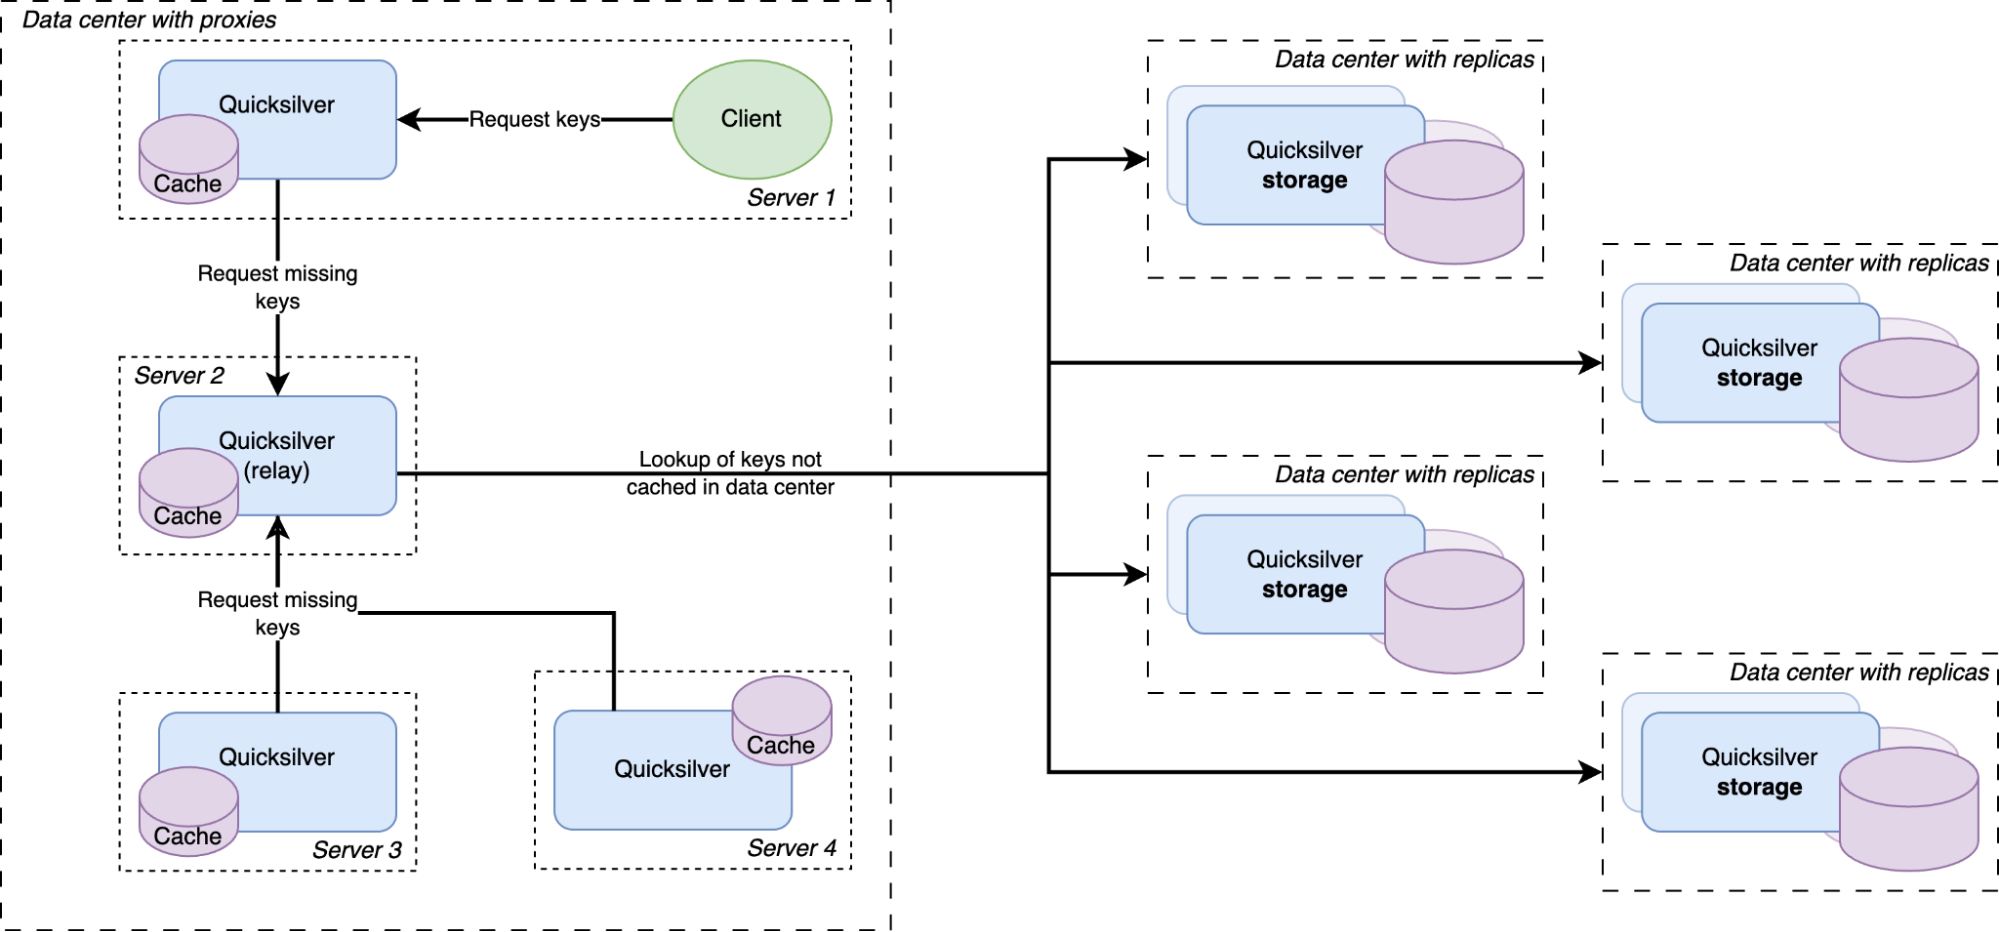
Except for a handful of special storage servers, Quicksilver does not contain the full dataset anymore, but only cache. Any cache misses will be looked up in replicas on our storage servers, which do have the full dataset.

The solution to the scalability problem was brought on by a new insight. As it turns out, numerous key-values were actually almost never used. We call these cold keys. There are different reasons for these cold keys: some of them were old and not well cleaned up, some were used only in certain regions or in certain data centers, and some were not used for a very long time or maybe not at all (a domain name that is never looked up for example or a script that was uploaded but never used).

At first, the team had been considering solving our scalability problem by splitting up the entire dataset into shards and distributing those across the servers in the different data centers. But sharding the full dataset adds a lot of complexity, corner cases, and unknowns. Sharding also does not optimize for data locality. For example, if the key-space is split into 4 shards and each server gets one shard, that server can only serve 25% of the requested keys from its local database. The cold keys would also still be contained in those shards and would take up disk space unnecessarily.

Another data structure that is much better at data locality and explicitly avoids storing keys that are never used is a cache. So it was decided that only a handful of servers with large disks would maintain the full data set, and all other servers would only have a cache. This was an obvious evolution from Quicksilver V1.5. Caching was already being done on a smaller scale, so all the components were already available. The caching proxies and the inter-data center discovery mechanisms were already in place. They had been used since 2021 and were therefore thoroughly battle tested. However, one more component needed to be added.

There was a concern that having all instances on all servers connect to a handful of storage nodes with replicas would overload them with too many connections. So a Quicksilver relay was added. For each instance, a few servers would be elected within each data center on which Quicksilver would run in relay mode. The relays would maintain the connections to the replicas on the storage nodes. All proxies inside a data center would discover those relays and all cache misses would be relayed through them to the replicas.

This new architecture worked very well. The cache hit rates still needed some improvement, however.

Prefetching the future


Every resolved cache miss is prefetched by all servers in the data center

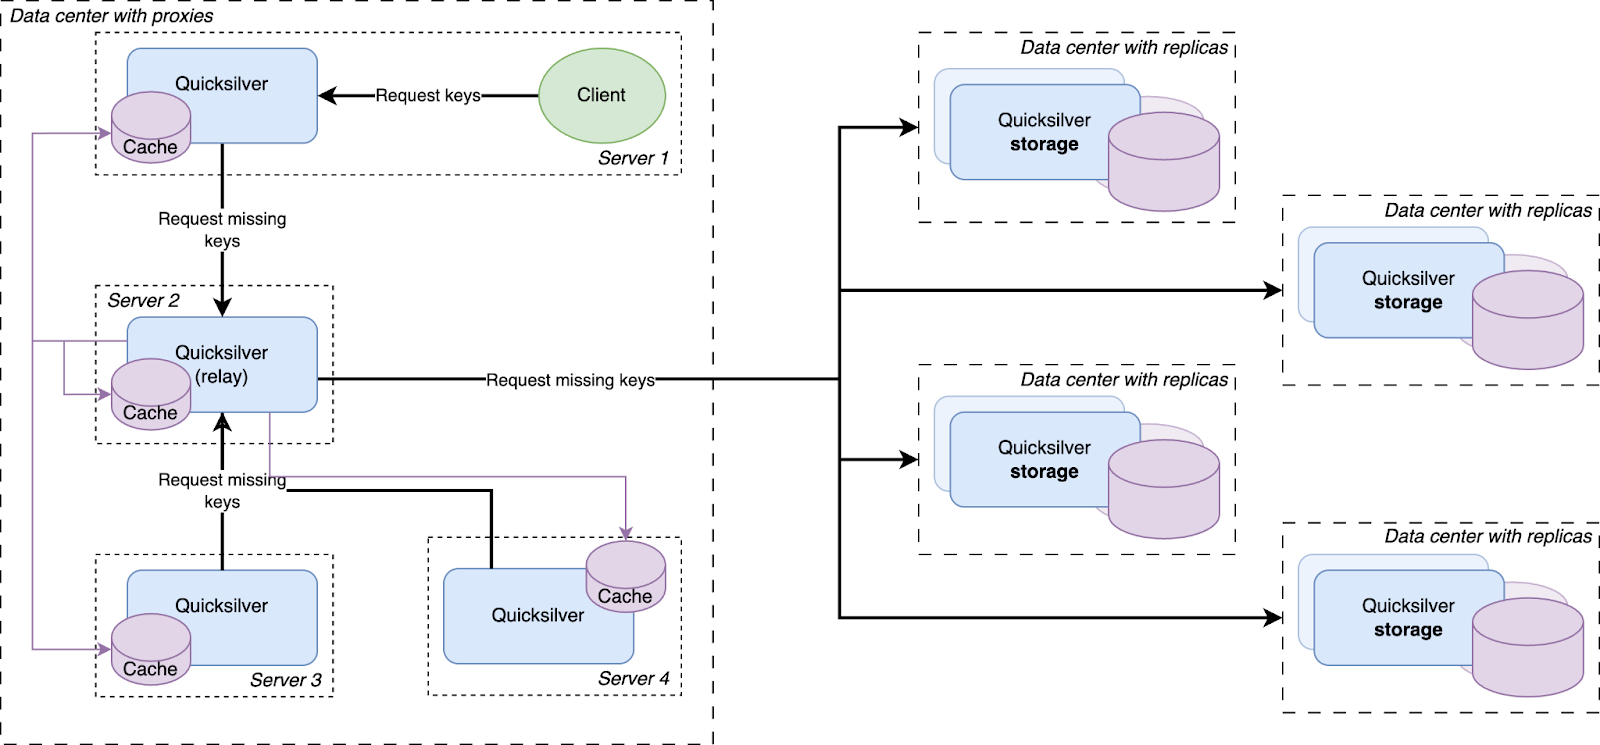
We had a hypothesis that prefetching all keys that were cache misses on the other servers inside the same data center would improve the cache hit rate. So an analysis was done, and it indeed showed that every key that was a cache miss on one server in a data center had a very high probability of also being a cache miss on another server in the same data center sometime in the near future. Therefore, a mechanism was built that distributed all resolved cache misses on relays to all other servers.

All cache misses in a data center are resolved by requesting them from a relay, which subsequently forwards the requests to one of the replicas on the storage nodes. Therefore, the prefetching mechanism was implemented by making relays publish a stream of all resolved cache misses, to which all Quicksilver proxies in the same data center subscribe. The resulting key-values were then added to the proxy local caches.

This strategy is called reactive prefetching, because it fills caches only with the key-values that directly resulted from cache misses inside the same data center. Those prefetches are a reaction to the cache misses. Another way of prefetching is called predictive prefetching, in which an algorithm tries to predict which keys that have not yet been requested will be requested in the near future. A few approaches for making these predictions were tried, but they did not result in any improvement, and so this idea was abandoned.

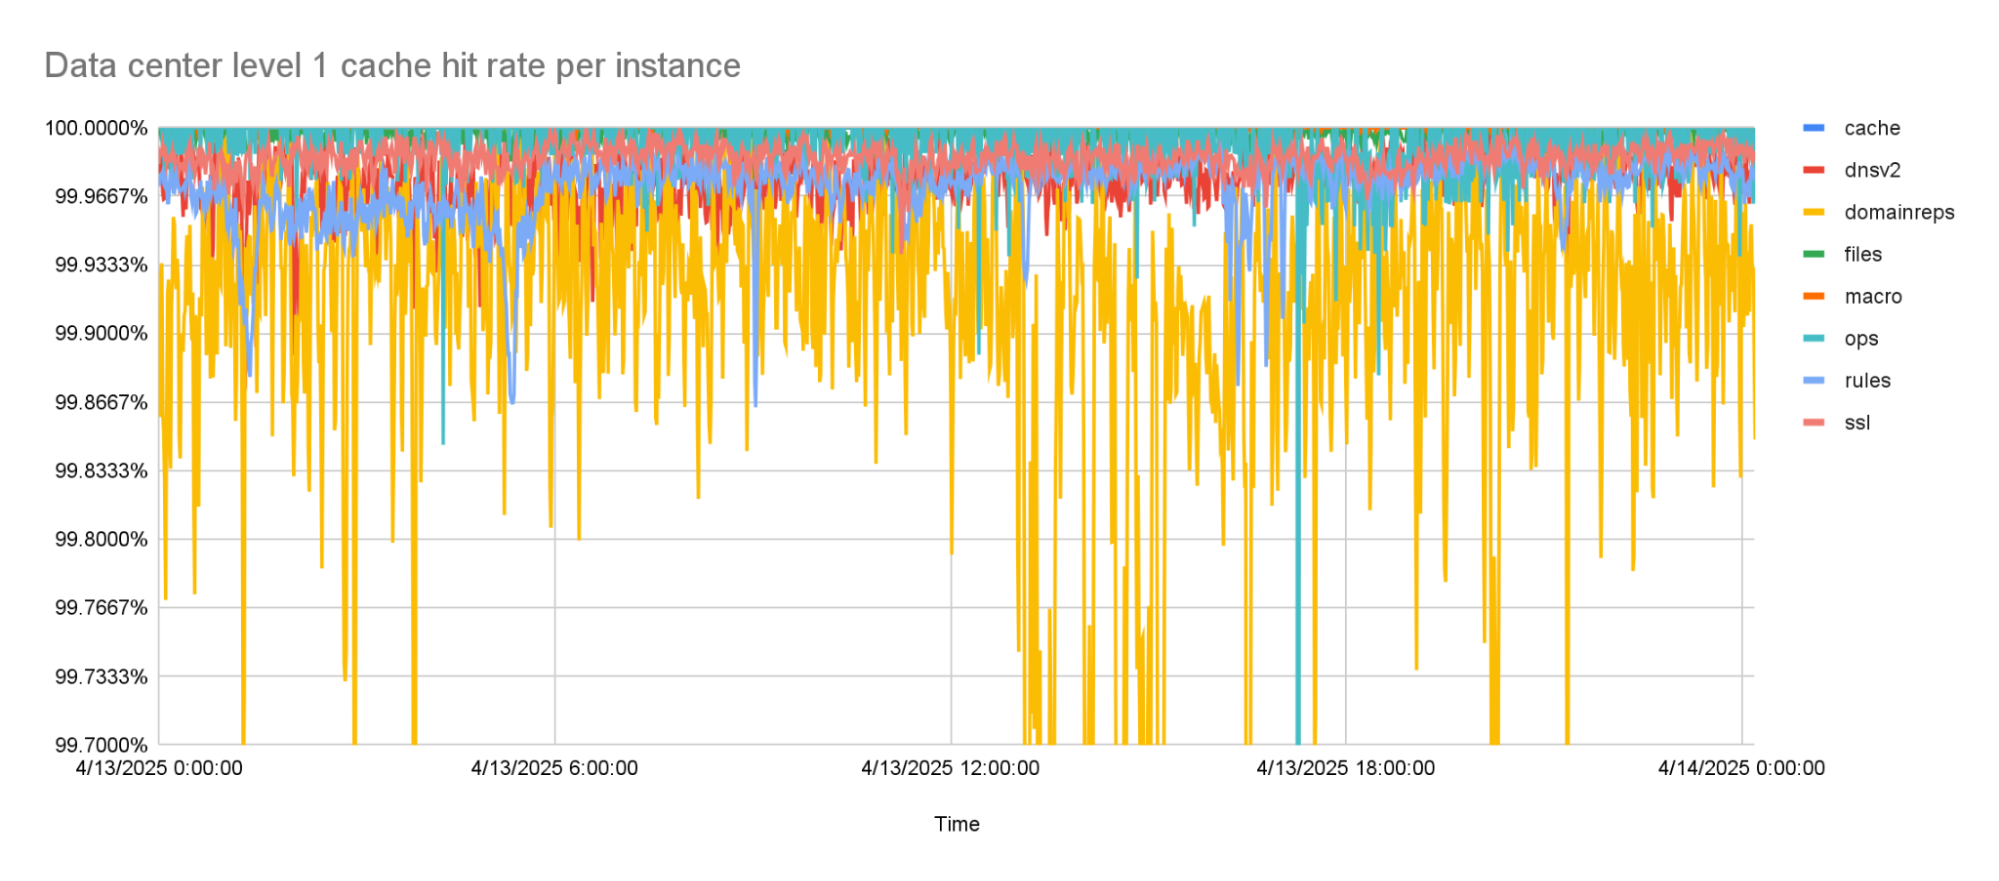
With the prefetching enabled, cache hit rates went up to about 99.9% for the worst performing instance. This was the goal that we were trying to reach. But while rolling this out to more of our network, it turned out that there was one team that needed an even higher cache hit rate, because the tail latencies they were seeing with this new architecture were too high.

This team was using a Quicksilver instance called dnsv2. This is a very latency sensitive instance, because it is the one from which DNS queries are served. Some of the DNS queries under the hood need multiple queries to Quicksilver, so any added latency to Quicksilver multiplies for them. This is why it was decided that one more improvement to the Quicksilver cache was needed.


The level 1 cache hit-rate is 99.9% or higher, on average.

Back to the sharding


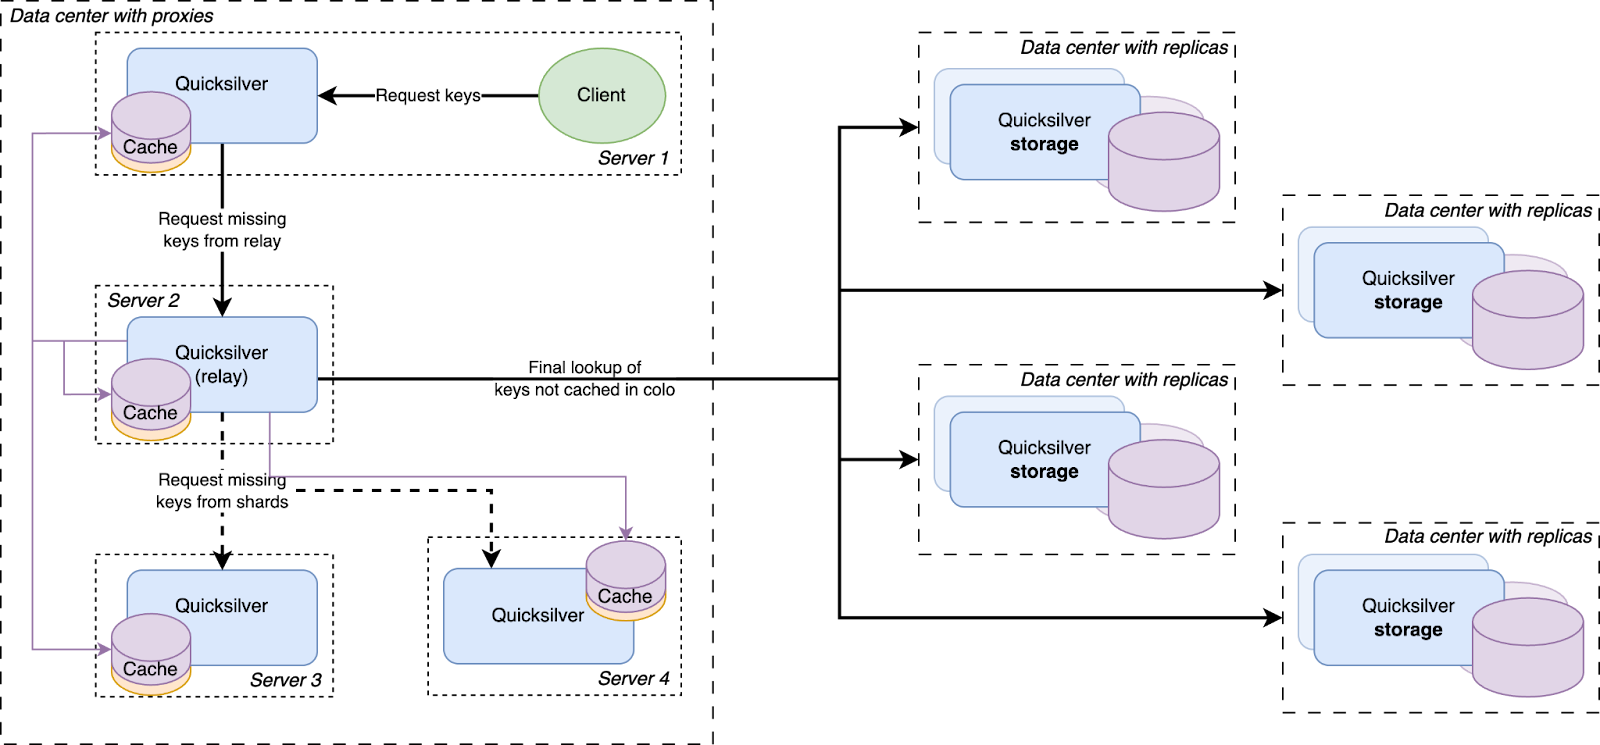
Before going to a replica in another data center, a cache miss is first looked up in a data center-wide sharded cache

The instance on which higher cache hit rates were required was also the instance on which the cache performed the worst. The cache works with a retention time, defined as the number of days a key-value is kept in cache after it was last accessed, after which it is evicted from the cache. An analysis of the cache showed that this instance needed a much longer retention time. But, a higher retention time also causes the cache to take up more disk space — space that was not available.

However, while running Quicksilver V1.5, we had already noticed the pattern that caches generally performed much better in smaller data centers as compared to larger ones. This sparked the hypothesis that led to the final improvement.

It turns out that smaller data centers, with fewer servers, generally needed less disk space for their cache. Vice versa, the more servers there are in a data center, the larger the Quicksilver cache needs to be. This is easily explained by the fact that larger data centers generally serve larger populations, and therefore have a larger diversity of requests. More servers also means more total disk space available inside the data center. To be able to make use of this pattern the concept of sharding was reintroduced.

Our key space was split up into multiple shards. Each server in a data center was assigned one of the shards. Instead of those shards containing the full dataset for their part of the key space, they contain a cache for it. Those cache shards are populated by all cache misses inside the data center. This all forms a data center-wide cache that is distributed using sharding.

The data locality issue that sharding the full dataset has, as described above, is solved by keeping the local per-server caches as well. The sharded cache is in addition to the local caches. All servers in a data center contain both their local cache and a cache for one physical shard of the sharded cache. Therefore, each requested key is first looked up in the server’s local cache, after that the data center-wide sharded cache is queried, and finally if both caches miss the requested key, it is looked up on one of the storage nodes.

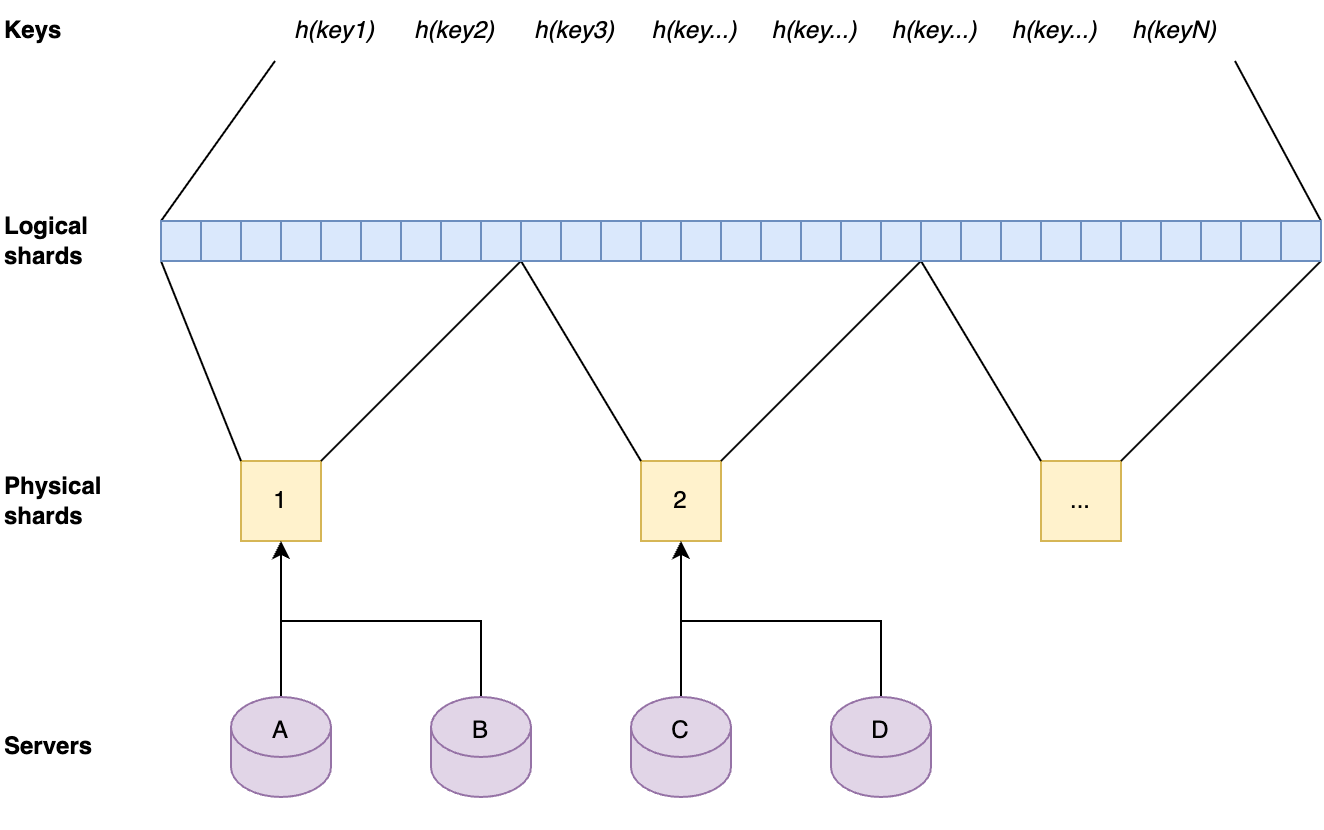
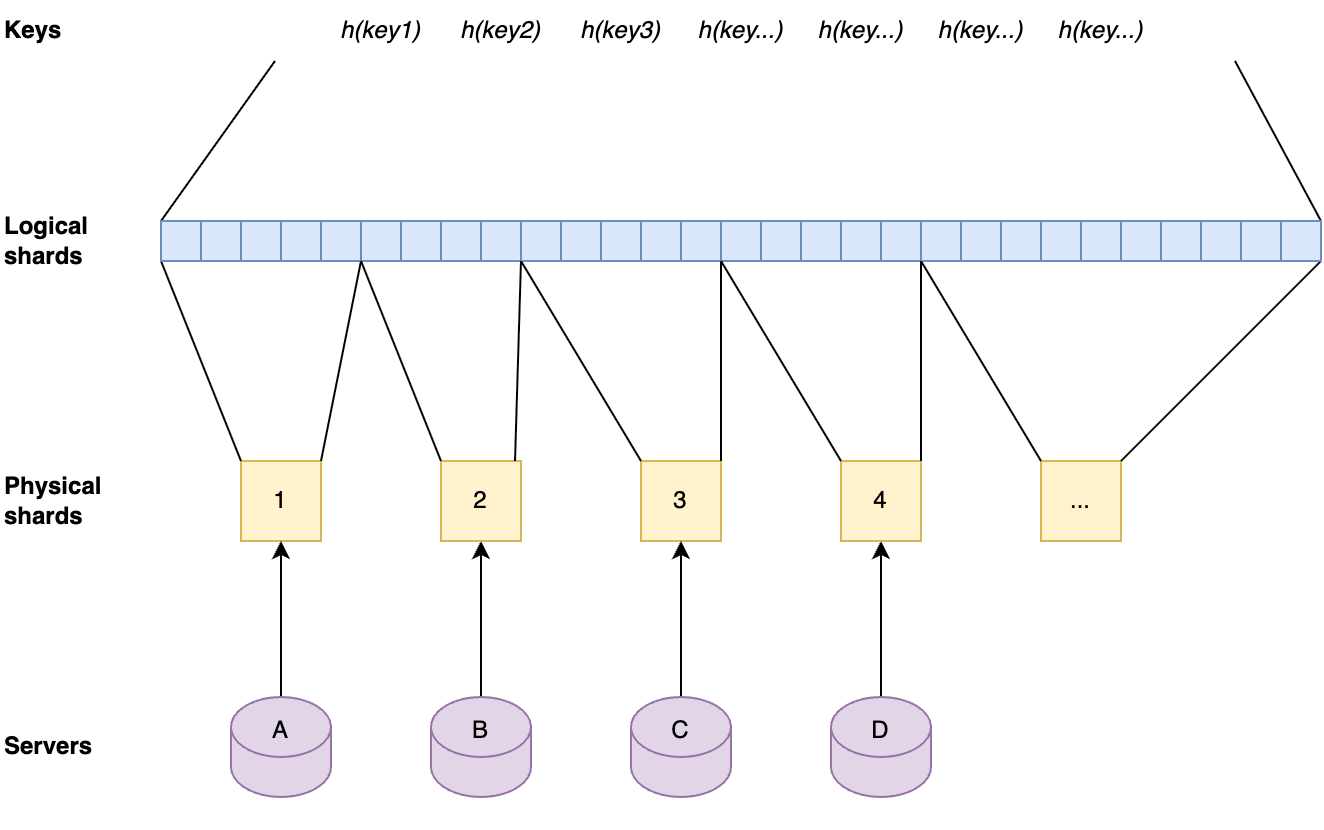
The key space is split up into separate shards by first dividing hashes of the keys by range into 1024 logical shards. Those logical shards are then divided up into physical shards, again by range. Each server gets one physical shard assigned by repeating the same process on the server hostname.


Each server contains one physical shard. A physical shard contains a range of logical shards. A local shard contains a range of the ordered set that result from hashing all keys.

This approach has the advantage that the sharding factor can be scaled up by factors of two without the need for copying caches to other servers. When the sharding factor is increased in this way, the servers will automatically get a new physical shard assigned that contains a subset of the key space that the previous physical shard on that server contained. After this has happened, their cache will contain supersets of the needed cache. The key-values that are not needed anymore will be evicted over time.


When the number of physical shards are doubled the servers will automatically get new physical shards that are subsets of their previous physical shards, therefore still have the relevant key-values in cache.

This approach means that the sharded caches can easily be scaled up when needed as the number of keys that are in Quicksilver grows, and without any need for relocating data. Also, shards are well-balanced due to the fact that they contain uniform random subsets of a very large key-space.

Adding new key-values to the physical cache shards piggybacks on the prefetching mechanism, which already distributes all resolved cache misses to all servers in a data center. The keys that are part of the key space for a physical shard on a particular server are just kept longer in cache than the keys that are not part of that physical shard.

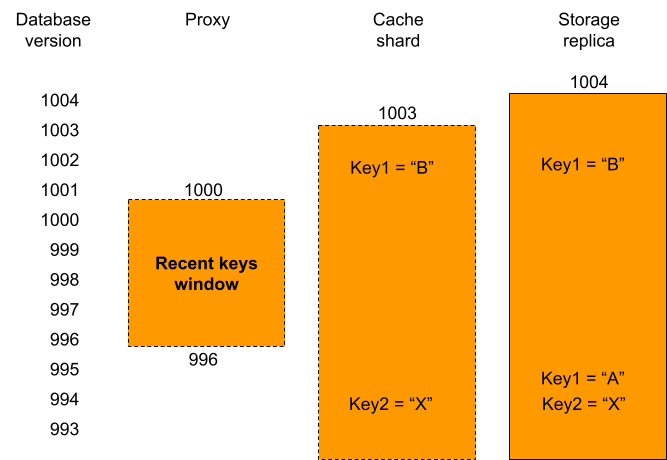
Another reason why a sharded cache is simpler than sharding the full key-space is that it is possible to cut some corners with a cache. For instance, looking up older versions of key-values (as used for  multiversion concurrency control) is not supported on cache shards. As explained in an earlier blog post, this is needed for consistency when looking up key-values on different servers, when that server has a newer version of the database. It is not needed in the cache shards, because lookups can always fall back to the storage nodes when the right version is not available.


Proxies have a recent keys window that contains all recently written key-values. A cache shard only has its cached key-values. Storage replicas contain all key-values and on top of that they contain multiple versions for recently written key-values. When the proxy, that has database version 1000, has a cache miss for key1 it can be seen that the version of that key on the cache shard was written at database version 1002 and therefore is too new. This means that it is not consistent with the proxy’s database version. This is why the relay will fetch that key from a replica instead, which can return the earlier consistent version. In contrast, key2 on the cache shard can be used, because it was written at index 994, well below the database version of the proxy.

There is only one very specific corner case in which a key-value on a cache shard cannot be used. This happens when the key-value in the cache shard was written at a more recent database version than the version of the proxy database at that time. This would mean that the key-value probably has a different value than it had at the correct version. Because, in general, the cache shard and the proxy database versions are very close to each other, and this only happens for key-values that were written in between those two database versions, this happens very rarely. As such, deferring the lookup to storage nodes has no noticeable effect on the cache hit rate.

Tiered Storage


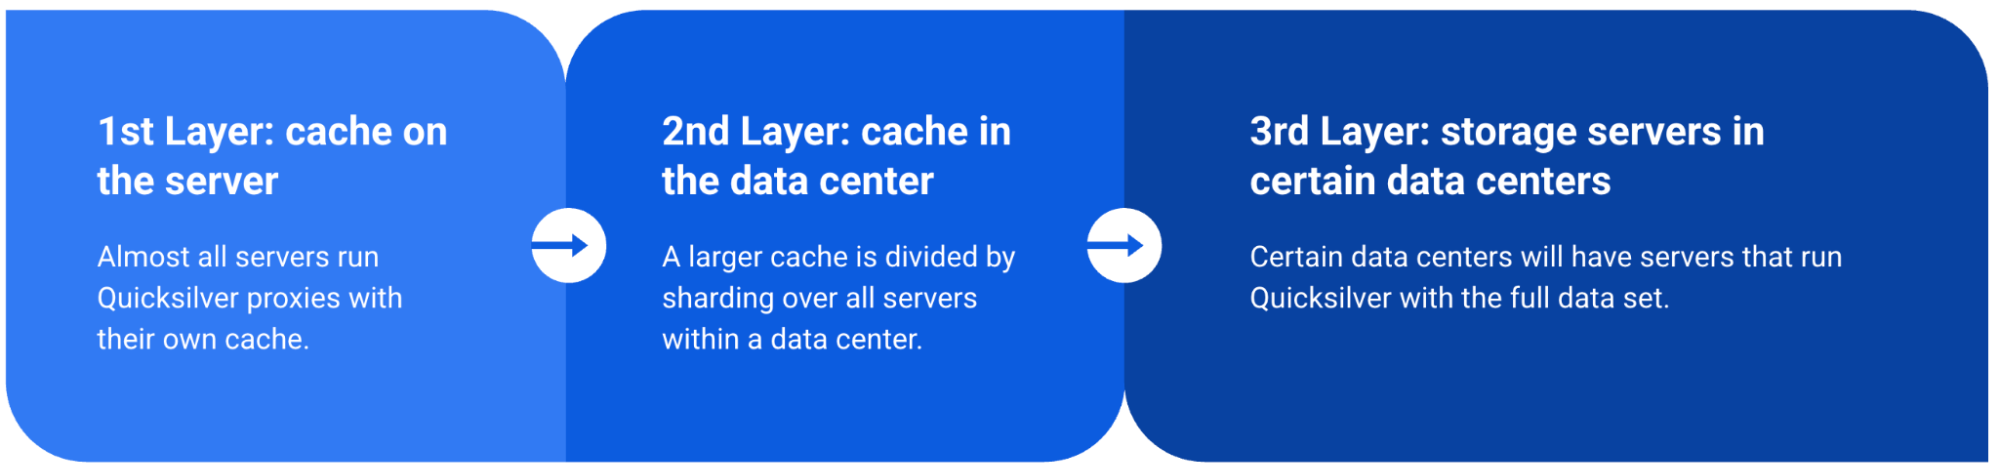
To summarize, Quicksilver V2 has three levels of storage.

  1. Level 1: The local cache on each server that contains the key-values that have most recently been accessed.

  2. Level 2: The data center wide sharded cache that contains key-values that haven’t been accessed in a while, but do have been accessed.

  3. Level 3: The replicas on the storage nodes that contain the full dataset, which live on a handful of storage nodes and are only queried for the cold keys.

The results

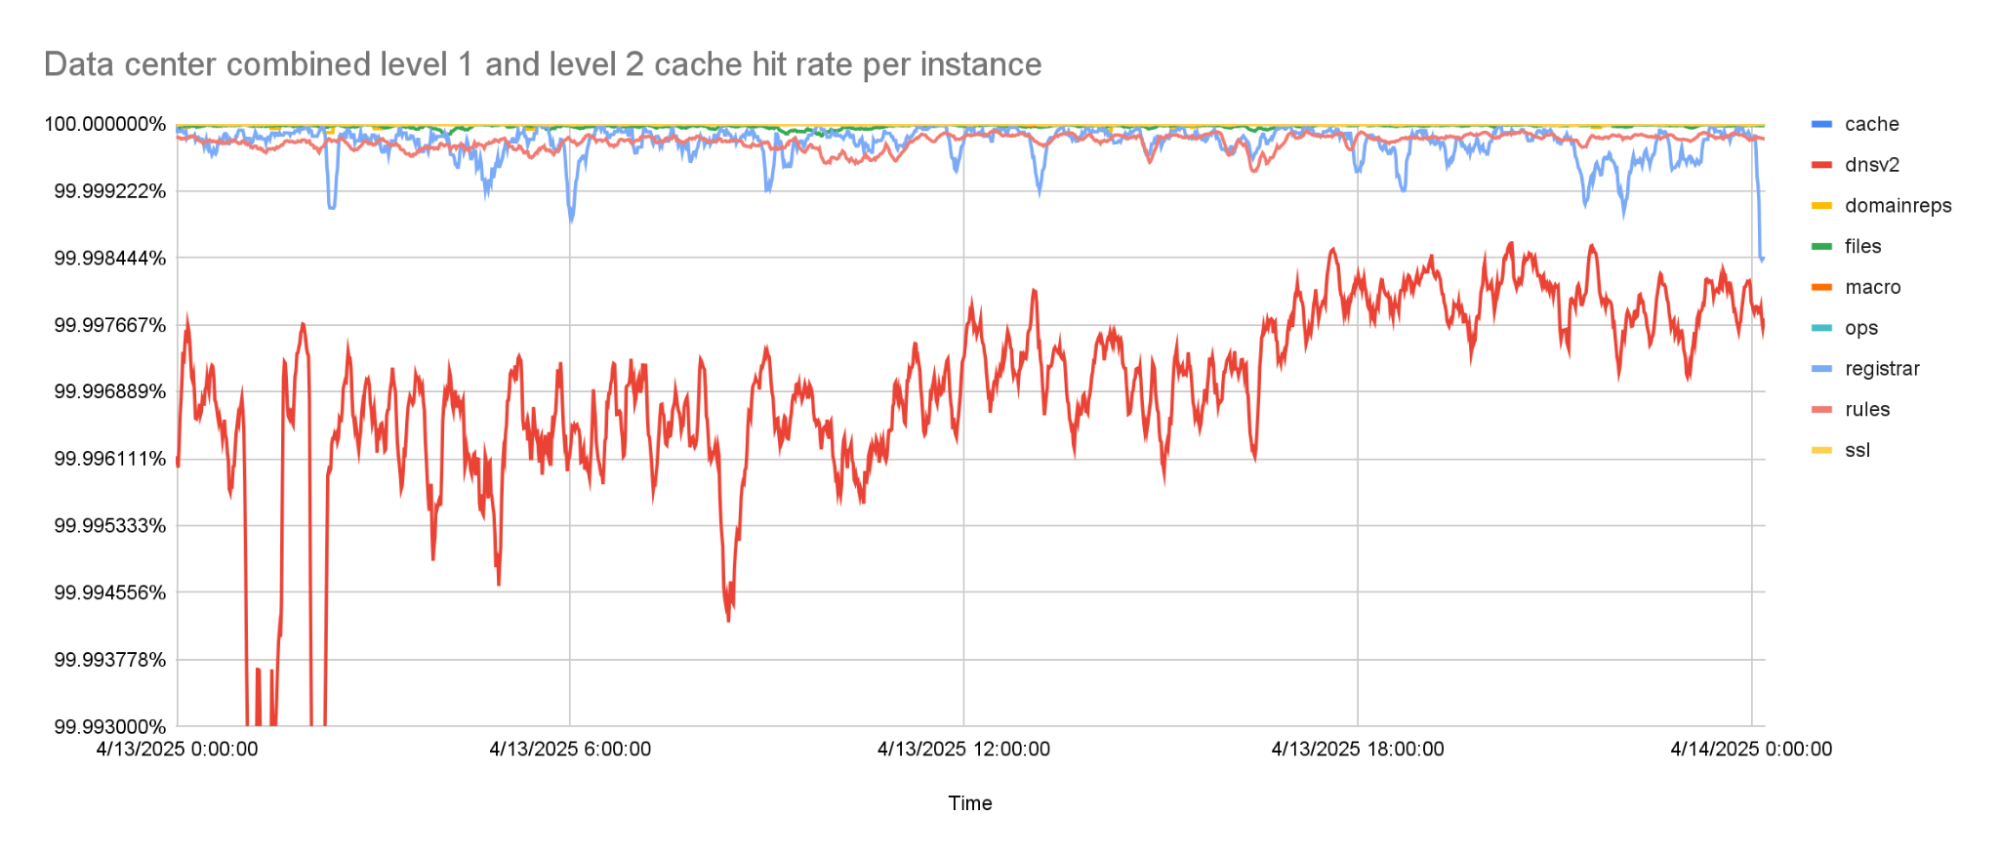
The percentage of keys that can be resolved within a data center improved significantly by adding the second caching layer. The worst performing instance has a cache hit rate higher than 99.99%. All other instances have a cache hit rate that is higher than 99.999%.


The combined level 1 and level 2 cache hit-rate is 99.99% or higher for the worst caching instance.

Final notes

It took the team quite a few years to go from the old Quicksilver V1, where all data was stored on each server to the tiered caching Quicksilver V2, where all but a handful of servers only have cache. We faced many challenges, including migrating hundreds of thousands of live databases without interruptions, while serving billions of requests per second. A lot of code changes were rolled out, with the result that Quicksilver now has a significantly different architecture. All of this was done transparently to our customers. It was all done iteratively, always learning from the previous step before taking the next one. And always making sure that, if at all possible, all changes are easy to revert. These are important strategies for migrating complex systems safely.

If you like these kinds of stories, keep an eye out for more development stories on our blog. And if you are enthusiastic about solving these kinds of problems, we are hiring for multiple types of roles across the organization

Thank you

And finally, a big thanks to the rest of the Quicksilver team, because we all do this together: Aleksandr Matveev, Aleksei Surikov, Alex Dzyoba, Alexandra (Modi) Stana-Palade, Francois Stiennon, Geoffrey Plouviez, Ilya Polyakovskiy, Manzur Mukhitdinov, Volodymyr Dorokhov.

Introducing Amazon S3 Vectors: First cloud storage with native vector support at scale (preview)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-amazon-s3-vectors-first-cloud-storage-with-native-vector-support-at-scale/

Today, we’re announcing the preview of Amazon S3 Vectors, a purpose-built durable vector storage solution that can reduce the total cost of uploading, storing, and querying vectors by up to 90 percent. Amazon S3 Vectors is the first cloud object store with native support to store large vector datasets and provide subsecond query performance that makes it affordable for businesses to store AI-ready data at massive scale.

Vector search is an emerging technique used in generative AI applications to find similar data points to given data by comparing their vector representations using distance or similarity metrics. Vectors are numerical representation of unstructured data created from embedding models. You generate vectors using embedding models for fields inside your document and store vectors into S3 Vectors to search semantically.

S3 Vectors introduces vector buckets, a new bucket type with a dedicated set of APIs to store, access, and query vector data without provisioning any infrastructure. When you create an S3 vector bucket, you organize your vector data within vector indexes, making it simple for running similarity search queries against your dataset. Each vector bucket can have up to 10,000 vector indexes, and each vector index can hold tens of millions of vectors.

After creating a vector index, when adding vector data to the index, you can also attach metadata as key-value pairs to each vector to filter future queries based on a set of conditions, for example, dates, categories, or user preferences. As you write, update, and delete vectors over time, S3 Vectors automatically optimizes the vector data to achieve the best possible price-performance for vector storage, even as the datasets scale and evolve.

S3 Vectors is also natively integrated with Amazon Bedrock Knowledge Bases, including within Amazon SageMaker Unified Studio, for building cost-effective Retrieval-Augmented Generation (RAG) applications. Through its integration with Amazon OpenSearch Service, you can lower storage costs by keeping infrequent queried vectors in S3 Vectors and then quickly move them to OpenSearch as demands increase or to support real-time, low-latency search operations.

With S3 Vectors, you can now economically store the vector embeddings that represent massive amounts of unstructured data such as images, videos, documents, and audio files, enabling scalable generative AI applications including semantic and similarity search, RAG, and build agent memory. You can also build applications to support a wide range of industry use cases including personalized recommendations, automated content analysis, and intelligent document processing without the complexity and cost of managing vector databases.

S3 Vectors in action
To create a vector bucket, choose Vector buckets in the left navigation pane in the Amazon S3 console and then choose Create vector bucket.

Enter a vector bucket name and choose the encryption type. If you don’t specify an encryption type, Amazon S3 applies server-side encryption with Amazon S3 managed keys (SSE-S3) as the base level of encryption for new vectors. You can also choose server-side encryption with AWS Key Management Service (AWS KMS) keys (SSE-KMS). To learn more about managing your vector bucket, visit S3 Vector buckets in the Amazon S3 User Guide.

Now, you can create a vector index to store and query your vector data within your created vector bucket.

Enter a vector index name and the dimensionality of the vectors to be inserted in the index. All vectors added to this index must have exactly the same number of values.

For Distance metric, you can choose either Cosine or Euclidean. When creating vector embeddings, select your embedding model’s recommended distance metric for more accurate results.

Choose Create vector index and then you can insert, list, and query vectors.

To insert your vector embeddings to a vector index, you can use the AWS Command Line Interface (AWS CLI), AWS SDKs, or Amazon S3 REST API. To generate vector embeddings for your unstructured data, you can use embedding models offered by Amazon Bedrock.

If you’re using the latest AWS Python SDKs, you can generate vector embeddings for your text using Amazon Bedrock using following code example:

# Generate and print an embedding with Amazon Titan Text Embeddings V2.
import boto3 
import json 

# Create a Bedrock Runtime client in the AWS Region of your choice. 
bedrock= boto3.client("bedrock-runtime", region_name="us-west-2") 

The text strings to convert to embeddings.
texts = [
"Star Wars: A farm boy joins rebels to fight an evil empire in space", 
"Jurassic Park: Scientists create dinosaurs in a theme park that goes wrong",
"Finding Nemo: A father fish searches the ocean to find his lost son"]

embeddings=[]
#Generate vector embeddings for the input texts
for text in texts:
        body = json.dumps({
            "inputText": text
        })    
        # Call Bedrock's embedding API
        response = bedrock.invoke_model(
        modelId='amazon.titan-embed-text-v2:0',  # Titan embedding model 
        body=body)   
        # Parse response
        response_body = json.loads(response['body'].read())
        embedding = response_body['embedding']
        embeddings.append(embedding)

Now, you can insert vector embeddings into the vector index and query vectors in your vector index using the query embedding:

# Create S3Vectors client
s3vectors_client = boto3.client('s3vectors', region_name='us-west-2')

# Insert vector embedding
s3vectors.put_vectors( vectorBucketName="channy-vector-bucket",
  indexName="channy-vector-index", 
  vectors=[
{"key": "v1", "data": {"float32": embeddings[0]}, "metadata": {"id": "key1", "source_text": texts[0], "genre":"scifi"}},
{"key": "v2", "data": {"float32": embeddings[1]}, "metadata": {"id": "key2", "source_text": texts[1], "genre":"scifi"}},
{"key": "v3", "data": {"float32": embeddings[2]}, "metadata": {"id": "key3", "source_text":  texts[2], "genre":"family"}}
],
)

#Create an embedding for your query input text
# The text to convert to an embedding.
input_text = "List the movies about adventures in space"

# Create the JSON request for the model.
request = json.dumps({"inputText": input_text})

# Invoke the model with the request and the model ID, e.g., Titan Text Embeddings V2. 
response = bedrock.invoke_model(modelId="amazon.titan-embed-text-v2:0", body=request)

# Decode the model's native response body.
model_response = json.loads(response["body"].read())

# Extract and print the generated embedding and the input text token count.
embedding = model_response["embedding"]

# Performa a similarity query. You can also optionally use a filter in your query
query = s3vectors.query_vectors( vectorBucketName="channy-vector-bucket",
  indexName="channy-vector-index",
  queryVector={"float32":embedding},
  topK=3, 
  filter={"genre":"scifi"},
  returnDistance=True,
  returnMetadata=True
  )
results = query["vectors"]
print(results)

To learn more about inserting vectors into a vector index, or listing, querying, and deleting vectors, visit S3 vector buckets and S3 vector indexes in the Amazon S3 User Guide. Additionally, with the S3 Vectors embed command line interface (CLI), you can create vector embeddings for your data using Amazon Bedrock and store and query them in an S3 vector index using single commands. For more information, see the S3 Vectors Embed CLI GitHub repository.

Integrate S3 Vectors with other AWS services
S3 Vectors integrates with other AWS services such as Amazon Bedrock, Amazon SageMaker, and Amazon OpenSearch Service to enhance your vector processing capabilities and provide comprehensive solutions for AI workloads.

Create Amazon Bedrock Knowledge Bases with S3 Vectors
You can use S3 Vectors in Amazon Bedrock Knowledge Bases to simplify and reduce the cost of vector storage for RAG applications. When creating a knowledge base in the Amazon Bedrock console, you can choose the S3 vector bucket as your vector store option.

In Step 3, you can choose the Vector store creation method either to create an S3 vector bucket and vector index or choose the existing S3 vector bucket and vector index that you’ve previously created.

For detailed step-by-step instructions, visit Create a knowledge base by connecting to a data source in Amazon Bedrock Knowledge Bases in the Amazon Bedrock User Guide.

Using Amazon SageMaker Unified Studio
You can create and manage knowledge bases with S3 Vectors in Amazon SageMaker Unified Studio when you build your generative AI applications through Amazon Bedrock. SageMaker Unified Studio is available in the next generation of Amazon SageMaker and provides a unified development environment for data and AI, including building and texting generative AI applications that use Amazon Bedrock knowledge bases.

You can choose your knowledge bases using the S3 Vectors created through Amazon Bedrock when you build generative AI applications. To learn more, visit Add a data source to your Amazon Bedrock app in the Amazon SageMaker Unified Studio User Guide.

Export S3 vector data to Amazon OpenSearch Service
You can balance cost and performance by adopting a tiered strategy that stores long-term vector data cost-effectively in Amazon S3 while exporting high priority vectors to OpenSearch for real-time query performance.

This flexibility means your organizations can access OpenSearch’s high performance (high QPS, low latency) for critical, real-time applications, such as product recommendations or fraud detection, while keeping less time-sensitive data in S3 Vectors.

To export your vector index, choose Advanced search export, then choose Export to OpenSearch in the Amazon S3 console.

Then, you will be brought to the Amazon OpenSearch Service Integration console with a template for S3 vector index export to OpenSearch vector engine. Choose Export with pre-selected S3 vector source and a service access role.

It will start the steps to create a new OpenSearch Serverless collection and migrate data from your S3 vector index into an OpenSearch knn index.

Choose the Import history in the left navigation pane. You can see the new import job that was created to make a copy of vector data from your S3 vector index into the OpenSearch Serverless collection.

Once the status changes to Complete, you can connect to the new OpenSearch serverless collection and query your new OpenSearch knn index.

To learn more, visit Creating and managing Amazon OpenSearch Serverless collections in the Amazon OpenSearch Service Developer Guide.

Now available
Amazon S3 Vectors, and its integrations with Amazon Bedrock, Amazon OpenSearch Service, and Amazon SageMaker are now in preview in the US East (N. Virginia), US East (Ohio), US West (Oregon), Europe (Frankfurt), and Asia Pacific (Sydney) Regions.

Give S3 Vectors a try in the Amazon S3 console today and send feedback to AWS re:Post for Amazon S3 or through your usual AWS Support contacts.

— Channy

Quicksilver v2: evolution of a globally distributed key-value store (Part 1)

Post Syndicated from Anton Dort-Golts original https://blog.cloudflare.com/quicksilver-v2-evolution-of-a-globally-distributed-key-value-store-part-1/

Quicksilver is a key-value store developed internally by Cloudflare to enable fast global replication and low-latency access on a planet scale. It was initially designed to be a global distribution system for configurations, but over time it gained popularity and became the foundational storage system for many products in Cloudflare.

A previous post described how we moved Quicksilver to production and started replicating on all machines across our global network. That is what we called Quicksilver v1: each server has a full copy of the data and updates it through asynchronous replication. The design served us well for some time. However, as our business grew with an ever-expanding data center footprint and a growing dataset, it became more and more expensive to store everything everywhere.

We realized that storing the full dataset on every server is inefficient. Due to the uniform design, data accessed in one region or data center is replicated globally, even if it’s never accessed elsewhere. This leads to wasted disk space. We decided to introduce a more efficient system with two new server roles: replica, which stores the full dataset and proxy, which acts as a persistent cache, evicting unused key-value pairs to free up some disk space. We call this design Quicksilver v1.5 – an interim step towards a more sophisticated and scalable system.

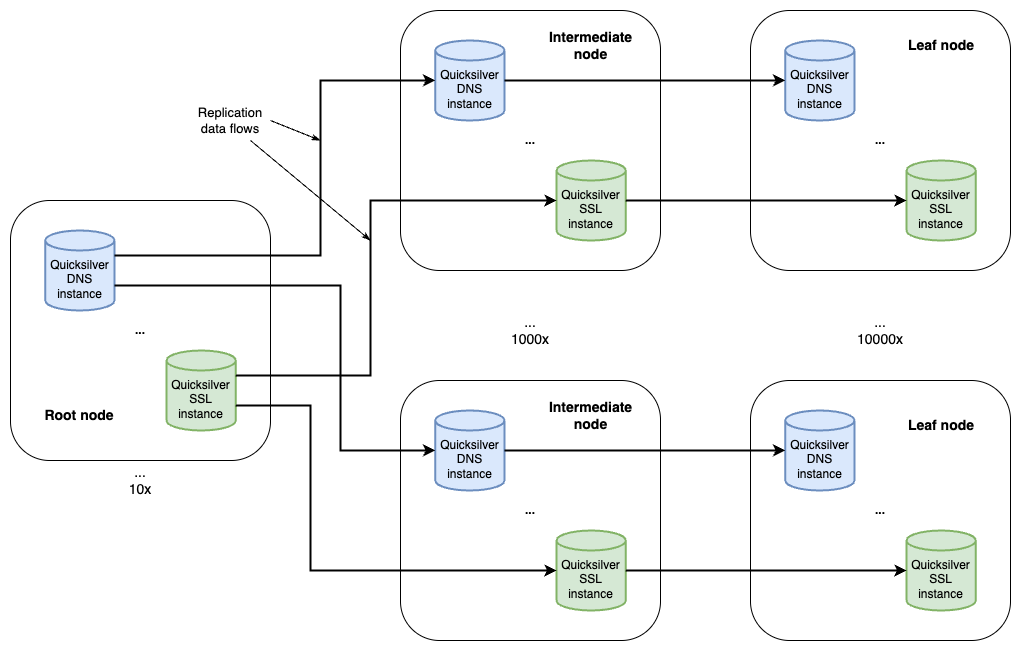
To understand how those two roles helped us reduce disk space usage, we first need to share some background on our setup and introduce some terminology. Cloudflare is architected in a way where we have a few hyperscale core data centers that form our control plane, and many smaller data centers distributed across the globe where resources are more constrained. Quicksilver has dozens of servers in the core data centers with terabytes of storage called root nodes. In the smaller data centers, though, things are different. A typical data center has two types of nodes: intermediate nodes and leaf nodes. Intermediate servers replicate data either from the other intermediate nodes or directly from the root nodes. Leaf nodes serve end user traffic, and receive updates from intermediate servers, effectively being leaves of a replication tree. Disk capacity varies significantly between node types. While root nodes aren’t facing an imminent disk space bottleneck, it’s a definite concern for leaf nodes.

Every server – whether it’s a root, intermediate, or leaf – hosts 10 Quicksilver instances. These are independent databases, each used by specific Cloudflare services or products such as the DNS, CDN  or WAF. 


Figure 1. Global Quicksilver

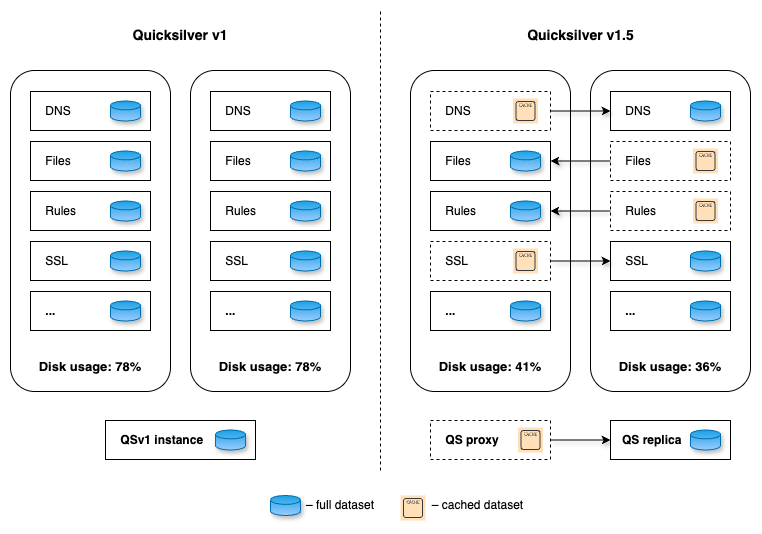
Let’s consider the role distribution. Instead of hosting ten full datasets on every machine within a data center, what if we deploy only a few replicas in each?  The remaining servers would be proxies, maintaining a persistent cache of hot keys and querying replicas for any cache misses.


Figure 2. Role allocation for different Quicksilver instances

Data centers across our network are very different in size, ranging from hundreds of servers to a single rack with just a few servers. To ensure every data center has at least one replica, the simplest initial step is an even split: on each server, place five replicas of some instances and five proxies for others. The change immediately frees up disk space, as the cached hot dataset on a proxy should be smaller than a full replica. While it doesn’t remove the bottleneck entirely, it could, in theory, lead to an up to 50% reduction in disk space usage. More importantly, it lays the foundation for a new distributed design of Quicksilver, where queries can be served by multiple machines in a data center, paving the way for further horizontal scaling. Additionally, an iterative approach helps to battle-proof the code changes earlier.

Can it even work?

Before committing to building Quicksilver v1.5, we wanted to be sure that the proxy/replica design would actually work for our workload. If proxies needed to cache the entire dataset for good performance, then it would be a dead end, offering no potential disk space benefits. To assess this, we built a data pipeline which pushes accessed keys from all across our network to ClickHouse. This allowed us to estimate typical sizes of working sets. Our analysis revealed that:

  • in large data centers approximately, 20% of the keyspace was in use

  • in small data centers this number dropped to just about 1%

These findings gave us confidence that the caching approach should work, though it wouldn’t be without its challenges.

Persistent caching

When talking about caches, the first thing that comes to mind is an in-memory cache. However, this cannot work for Quicksilver for two main reasons: memory usage and the “cold cache” problem.

Indeed, with billions of stored keys, even a fraction of them would lead to an unmanageable increase in memory usage. System restarts should not affect performance, which means that cache data must be preserved somewhere anyway. So we decided to make the cache persistent and store it in the same way as full datasets: in our embedded RocksDB. Thus, cached keys normally sit on disk and can be retrieved on-demand with low memory footprint.

When a key cannot be found in the proxy’s cache, we request it from a replica using our internal distributed key-value protocol, and put it into a local cache after processing.

Evictions are based on RocksDB compaction filters. Compaction filters allow defining custom logic executed in background RocksDB threads responsible for compacting files on disk. Each key-value pair is processed with a filter on a regular basis, evicting least recently used data from the disk when available disk space drops below a certain threshold called a soft limit. To track keys accessed on disk, we have an LRU-like in-memory data structure, which is passed to the compaction filter to set last access date in key metadata and inform potential evictions.

However, with some specific workloads there is still a chance that evictions will not keep up with disk space growth, and for this scenario we have a hard limit: when available disk space drops below a critical threshold, we temporarily stop adding new keys to the cache. This hurts performance, but it acts as a safeguard, ensuring our proxies remain stable and don’t overflow under a massive surge of requests.

Consistency and asynchronous replication

Quicksilver has, from the start, provided sequential consistency to clients: if key A was written before B, it’s not possible to read B and not A. We are committed to maintaining this guarantee in the new design. We have experienced Hyrum’s Law first hand, with Quicksilver being so widely adopted across the company that every property we introduced in earlier versions is now relied upon by other teams. This means that changing behaviour would inevitably break existing functionality and introduce bugs.

However, there is one thing standing in our way: asynchronous replication. Quicksilver replication is asynchronous mainly because machines in different parts of the world replicate at different speeds, and we don’t want a single server to slow down the entire tree. But it turns out in a proxy-replica design, independent replication progress can result in non-monotonic reads!

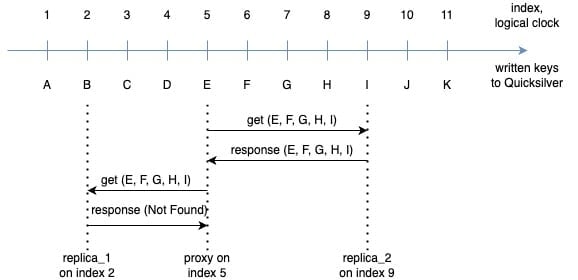
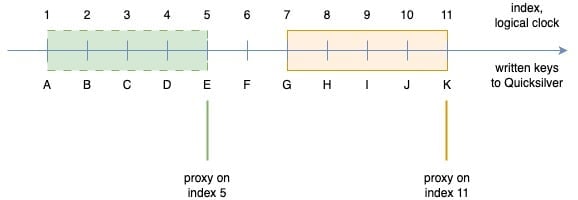
Consider the following scenario: a client sequentially writes keys A, B, C, .. K one after another to the Quicksilver root node. These keys are asynchronously replicated through data centers across our network with varying latency. Imagine we have a proxy on index 5, which has observed keys from A to E, and two replicas: 

  • replica_1 is at index 2 (slightly behind the proxy), having only received A and B

  • replica_2 at index 9, which is slightly ahead due to a faster replication path and has received all keys from A to I


Figure 3. Asynchronous replication in QSv1.5

Now, a client performs two successive requests on a proxy, each time reading the keys E, F, G, H and I. For simplicity, we assume these keys are not cacheable (for example, due to low disk space). The proxy’s first remote request is routed to replica_2, which already has all keys and responds back with values. To prevent hot spots in a data center, we load balance requests from proxies, and the next one lands on replica_1, which hasn’t received any of the requested keys yet, and responds with a “not found” error.

So, which result is correct?

The correct behavior here is that of Quicksilver v1, which we aim to preserve. If the server on replication index 5 were a replica instead of a proxy, it would have seen updates for keys A through E inclusive, resulting in E being the only key in both replies, while all other keys cannot be found yet. Which means responses from both replica_1 and replica_2 are wrong!

Therefore, to maintain previous guarantees and API backwards compatibility, Quicksilver v1.5 must address two crucial consistency problems: cases where the replica is ahead of the proxy, and conversely, where it lags behind. For now let’s focus on the case where a proxy lags behind a replica.

Multiversion concurrency control

In our example, replica_2 responds to a request from a proxy “from the past”. We cannot use any locks for synchronizing two servers, as it would introduce undesirable delays to the replication tree, defeating the purpose of asynchronous replication. The only option is for replicas to maintain a history of recent updates. This naturally leads us to implementing multiversion concurrency control (MVCC), a popular database mechanism for tracking changes in a non-blocking fashion, where for any key we can keep multiple versions of its values for different points in time.

With MVCC, we no longer overwrite the latest value of a key in the default column family for every update. Instead, we introduced a new MVCC column family in RocksDB, where all updates are stored with a corresponding replication index. Lookup for a key at some index in the past goes as follows:

  1. First we search in the default column family. If a key is found and the write timestamp is not greater than the index of a requesting proxy, we can use it straight away.

  2. Otherwise, we begin scanning the MVCC column family, where keys have unique suffixes based on latest timestamps for which they are still valid.

In the example above, replica_2 has MVCC enabled and has keys A@1 .. K@11 in its default column family. The MVCC is initially empty, because no keys have been overwritten yet. When it receives a request for, say, key H with target index 5, it first makes a lookup in a default column family and finds the given key, but its timestamp is 8, which means this version should not be visible to the proxy yet. It then scans the MVCC, finds no matching previous versions and responds with “not found” to the proxy. Should key H be updated twice at indexes 4 and 8, we would have placed the initial version into MVCC before overwriting it in the default column family, and the proxy would receive the first version in response.

If a key E is requested at index 5, replica_2 can find it quickly in the default column family and return it back to the proxy. There is no need to read from MVCC, as the timestamp of the latest version (5) satisfies the request.

Another corner case to consider is deletions. When a key is deleted and then re-written, we need to explicitly mark the period of removal in MVCC. For that we’ve implemented tombstones – a special value format for absent keys.

Finally, we need to make sure that key history is not growing uncontrollably, using up all of the disk space available. Luckily we don’t actually need to record history for a long period of time, it just needs to cover the maximum replication index difference between any two machines. And in practice, a two-hour interval turned out to be way more than enough, while adding only about 500 MB of extra disk space usage. All records in the MVCC column family older than two hours are garbage collected, and for that again we use custom RocksDB compaction filters.

Sliding window

Now we know how to deal with proxies lagging behind replicas. But what about the opposite case, when a proxy is ahead of replicas?

The simplest solution is for replicas to not serve requests with a target index higher than its own. After all, it cannot know about keys from the future, whether they will be added, updated, or removed. In fact, our first implementation just returned an error when the proxy was ahead, as we expected it to happen quite infrequently. But after rolling out gradually to a few data centers, our metrics made it clear that the approach was not going to work.

This led us to analyze which keys are affected by this kind of replication asymmetry. It’s definitely not keys added or updated a long time ago, because replicas would already have the changes replicated. The only problematic keys are those updated very recently, which the proxy already knows about, but the replica does not.

With this insight, we realized that the issue should be solved on the proxies rather than on the replica side. By preserving all recent updates locally, the proxy can avoid querying the replica. This became known as the sliding window approach.

The sliding window retains all recent updates written in a short, rolling timeframe. Unlike cached keys, items in the window cannot be evicted until they move outside of the window. Internally, the sliding window is defined by lower and upper boundary pointers. These are kept in memory, and can easily be restored after a reload from the current database index and the pre-configured window size.


Figure 4. The sliding window shifts when replication updates arrive

When a new update event arrives from the replication layer we add it to the sliding window by moving both the upper and lower boundary one position higher. Thereby, we maintain the fixed size of the window. Keys written before the lower bound can be evicted by the compaction filter, which is aware of current sliding window boundaries.

Negative lookups

Another problem arising with our distributed replica-proxy design is negative lookups – requests for keys which don’t exist in the database. Interestingly, in our workloads we see about ten times more negative lookups than positive ones!

But why is it a problem? Unfortunately, each negative lookup will be a cache miss on a proxy, requiring a request to a replica. Given the volume of requests and proportion of such lookups, it would be a disaster for performance, with overloaded replicas, overused data center networks, and massive latency degradation. We needed a fast and efficient approach to identifying non-existing keys directly at the proxy level.

In v1, negative lookups are the quickest type of requests. We rely on a special probabilistic data structure – Bloom filters – used in RocksDB to determine if the requested key might belong to a certain data file containing a range of sorted keys (called Sorted Sequence Table or SST) or definitely not. 99% of the time, negative lookups are served using only this in-memory data structure, avoiding the need for disk I/O.

One approach we considered for proxies was to cache negative lookups. Two problems immediately arise:

  • How big is the keyspace of negative lookups? In theory, it’s infinite, but the real size was unclear. We can store it in our cache only if it is small enough.

  • Cached negative lookups would no longer be served by the fast Bloom filters. We have row and block caches in RocksDB, but the hit rate is nowhere near the filters for SSTs, which means negative lookups would end up going to disk more often.

These turned out to be dealbreakers: not only was the negative keyspace vast, greatly exceeding the actual keyspace (by a thousand times for some instances!), but clients also need lookups to be really fast, ideally served from memory.

In pursuit of probabilistic data structures which could give us a dynamic compact representation of a full keyspace on proxies, we spent some time exploring Cuckoo filters. Unfortunately, with 5 billion keys it takes about 18 GB to have a false positive rate similar to Bloom filters (which only require 6 GB). And this is not only about wasted disk space — to be fast we have to keep it all in memory too!

Clearly some other solution was needed.

Finally, we decided to implement key and value separation, storing all keys on proxies, but persisting values only for cached keys. Evicting a key from the cache actually results in the removal of its value.

But wait, don’t the keys, even stripped of values, take a lot of space? Well, yes and no.

The total size of pure keys in Quicksilver is approximately 11 times smaller than the full dataset. Of course, it’s larger than any representation by probabilistic data structure, but there are some very desirable properties to such a solution. Firstly, we continue to enjoy fast Bloom filter lookups in RocksDB. Another benefit is that it unlocks some cool optimizations for range queries in a distributed context.

We may revisit it one day, but so far it has worked great for us.

Discovery mechanism

Having solved all of the above challenges, one bit remained to be sorted out to make distributed query execution work: how can proxies discover replicas?

Within the local data center it is fairly easy. Each one runs its own consul cluster, where machines are registered as services. Consul is well integrated with our internal DNS resolvers, and with a single DNS request, we can get the names of all replicas running in a data center, which proxies can directly connect to.

However, data centers vary in size, servers are constantly added and removed, and having only local discovery would not be enough for the system to work reliably. Proxies also need to find replicas in other nearby data centers.

We had previously encountered a similar problem with our replication layer. Initially, the replication topology was statically defined in a configuration and distributed to all servers, such that they know from which sources they should replicate. While simple, this approach was quite fragile and tedious to operate. It led to a rigid replication tree with suboptimal overall performance, unable to adapt to network changes.

Our solution to this problem was the Network Oracle – a special overlay network based on a gossip protocol and consisting of intermediate nodes in our data centers. Each member of this overlay constantly exchanges status and metainformation with other nodes, which helps us see active members in near-real time. Each member runs network probes measuring round-trip time to its peers, making it easy to find closest (in terms of RTT) active intermediate nodes to form a low-latency replication tree. Introducing the Network Oracle was a major improvement: we no longer needed to reconfigure the topology, watch intermediate nodes or entire data centers go down, or investigate frequent replication issues. Replication is now a completely self-organized and self-healing dynamic system.

Naturally, we decided to reuse the Network Oracle for our discovery mechanism. It consists of two subproblems: data center discovery and specific service lookup. We use the Network Oracle to find the closest data centers. Adding all machines running Quicksilver to the same overlay would be inefficient because of significant increase of network traffic and message delivery times. Instead, we use intermediate nodes as sources of network proximity information for the leaf nodes. Knowing which data centers are nearby, we can directly send DNS queries there to resolve specific services – Quicksilver replicas in this case.

Proxies maintain a pool of connections to active replicas and distribute requests among them to smooth out the load and avoid hotspots in a data center. Proxies also have a health-tracking mechanism, monitoring the state of connections and errors coming from replicas, and temporarily deprioritizing or isolating potentially faulty ones.


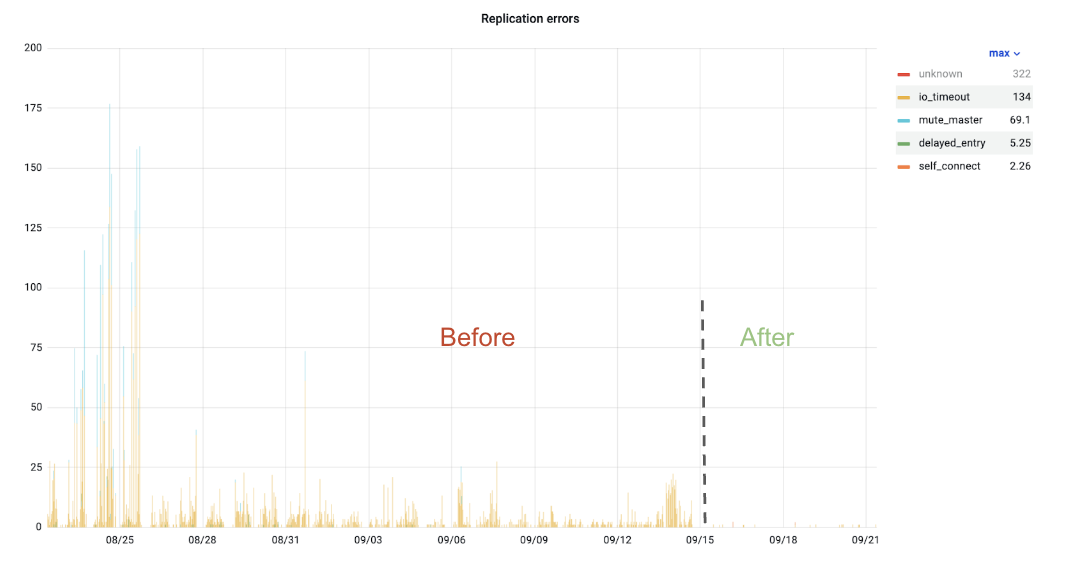
Figure 5. Internal replica request errors

To demonstrate its efficiency, we graphed errors coming from replica requests, which showed that such errors almost disappeared after introducing the new discovery system.

Results

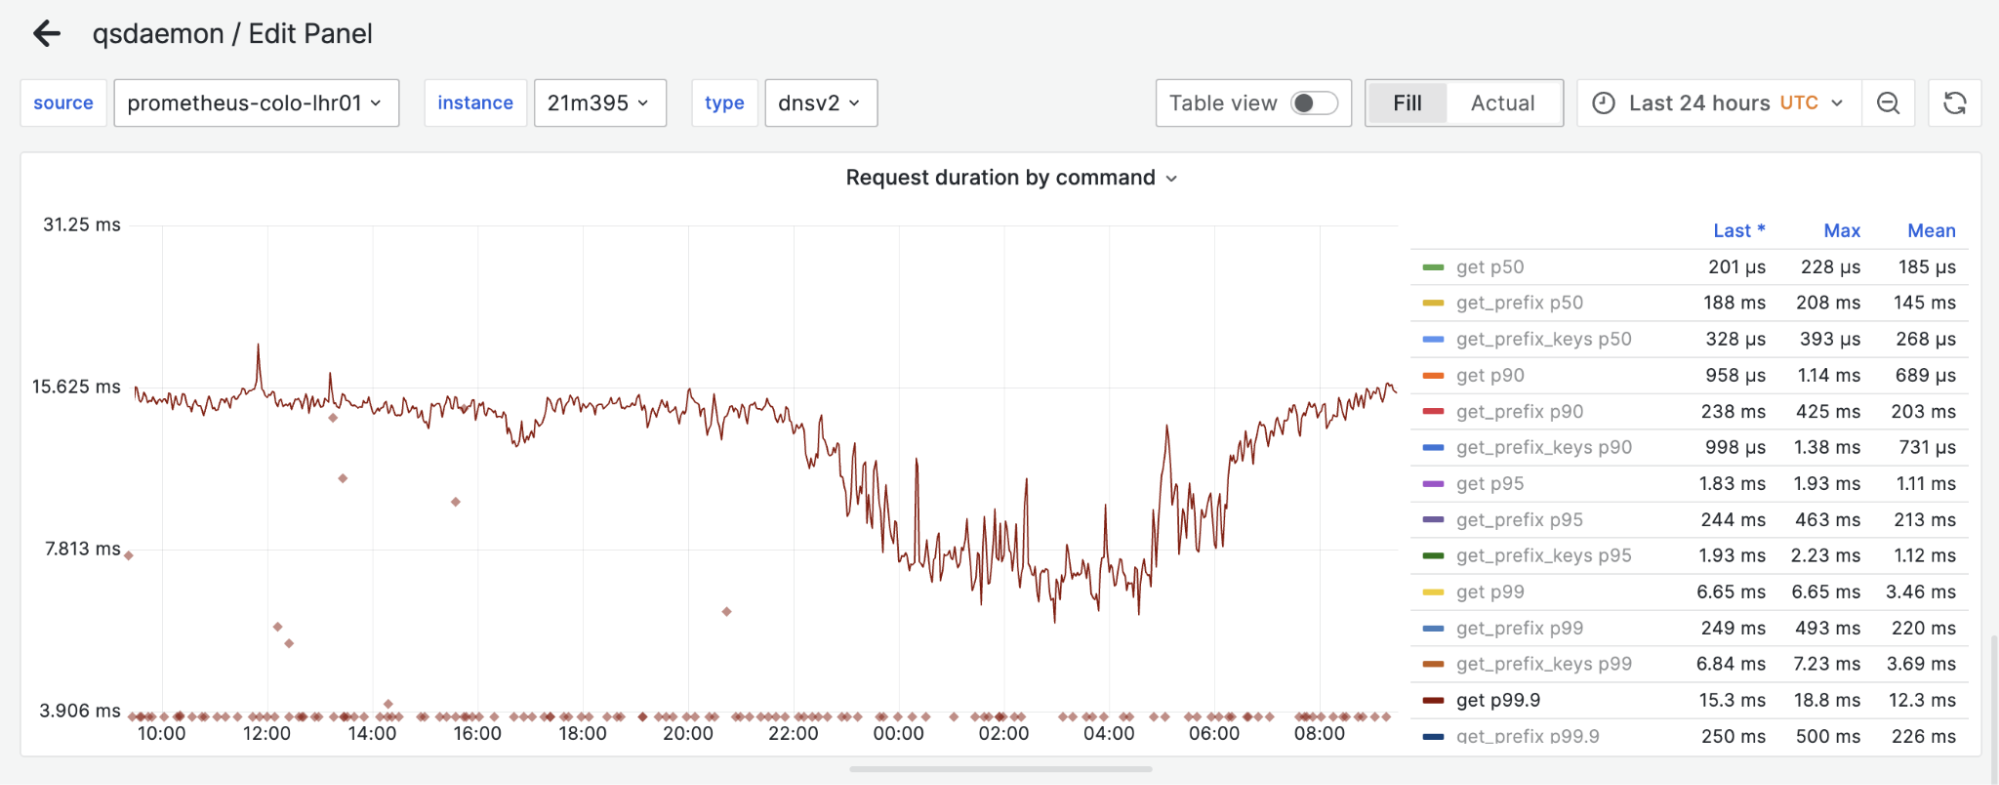
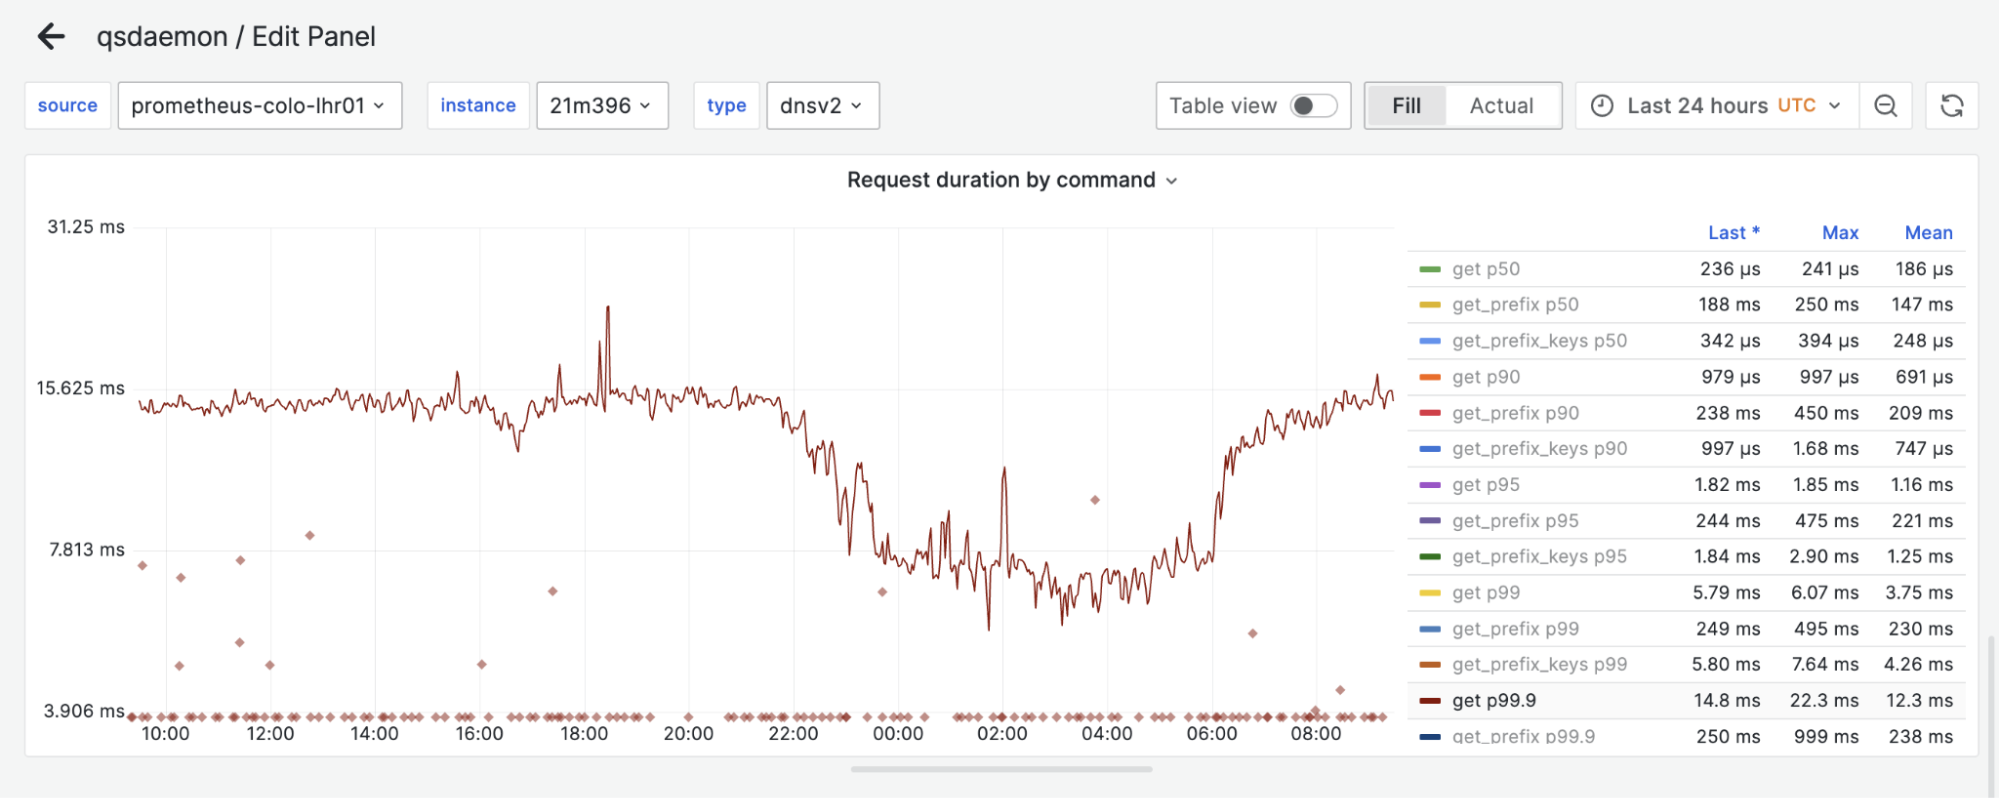
Our objective with Quicksilver v1.5 was simple: gain some disk space without losing request latency, because clients rely heavily on us being fast. While the replica-proxy design delivered significant space savings, what about latencies?

Proxy


Replica


Figure 6. Proxy-replica latency comparison

Above, we have the 99.9% percentile of request latency on both a replica and proxy during a 24-hour window. One can hardly find a difference between the two. Surprisingly, proxies can even be slightly faster than replicas sometimes, likely because of smaller datasets on disk!

Quicksilver v1.5 is released but our journey to a highly scalable and efficient solution is not over. In the next post we’ll share what challenges we faced with the following iteration. Stay tuned!

Thank you

This project was a big team effort, so we’d like to thank everyone on the Quicksilver team – it would not have come true without you all.

  • Aleksandr Matveev

  • Aleksei Surikov

  • Alex Dzyoba

  • Alexandra (Modi) Stana-Palade

  • Francois Stiennon

  • Geoffrey Plouviez

  • Ilya Polyakovskiy

  • Manzur Mukhitdinov

  • Volodymyr Dorokhov

Kioxia CD9P Showing the Power of New BiCS FLASH at HPE Discover 2025

Post Syndicated from Eric Smith original https://www.servethehome.com/kioxia-cd9p-showing-the-power-of-new-bics-flash-at-hpe-discover-2025/

We got to witness the power of new Kioxia BiCS FLASH generation 8 technology with a Kioxia CD9P versus CD8P demo at HPE Discover 2025

The post Kioxia CD9P Showing the Power of New BiCS FLASH at HPE Discover 2025 appeared first on ServeTheHome.

Amazon FSx for OpenZFS now supports Amazon S3 access without any data movement

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/amazon-fsx-for-openzfs-now-supports-amazon-s3-access-without-any-data-movement/

Starting today, you can attach Amazon S3 Access Points to your Amazon FSx for OpenZFS file systems to access your file data as if it were in Amazon Simple Storage Service (Amazon S3). With this new capability, your data in FSx for OpenZFS is accessible for use with a broad range of Amazon Web Services (AWS) services and applications for artificial intelligence, machine learning (ML), and analytics that work with S3. Your file data continues to reside in your FSx for OpenZFS file system.

Organizations store hundreds of exabytes of file data on premises and want to move this data to AWS for greater agility, reliability, security, scalability, and reduced costs. Once their file data is in AWS, organizations often want to do even more with it. For example, they want to use their enterprise data to augment generative AI applications and build and train machine learning models with the broad spectrum of AWS generative AI and machine learning services. They also want the flexibility to use their file data with new AWS applications. However, many AWS data analytics services and applications are built to work with data stored in Amazon S3 as data lakes. After migration, they can use tools that work with Amazon S3 as their data source. Previously, this required data pipelines to copy data between Amazon FSx for OpenZFS file systems and Amazon S3 buckets.

Amazon S3 Access Points attached to FSx for OpenZFS file systems remove data movement and copying requirements by maintaining unified access through both file protocols and Amazon S3 API operations. You can read and write file data using S3 object operations including GetObject, PutObject, and ListObjectsV2. You can attach hundreds of access points to a file system, with each S3 access point configured with application-specific permissions. These access points support the same granular permissions controls as S3 access points that attach to S3 buckets, including AWS Identity and Access Management (IAM) access point policies, Block Public Access, and network origin controls such as restricting access to your Virtual Private Cloud (VPC). Because your data continues to reside in your FSx for OpenZFS file system, you continue to access your data using Network File System (NFS) and benefit from existing data management capabilities.

You can use your file data in Amazon FSx for OpenZFS file systems to power generative AI applications with Amazon Bedrock for Retrieval Augmented Generation (RAG) workflows, train ML models with Amazon SageMaker, and run analytics or business intelligence (BI) with Amazon Athena and AWS Glue as if the data were in S3, using the S3 API. You can also generate insights using open source tools such as Apache Spark and Apache Hive, without moving or refactoring your data.

To get started
You can create and attach an S3 Access Point to your Amazon FSx for OpenZFS file system using the Amazon FSx console, the AWS Command Line Interface (AWS CLI), or the AWS SDK.

To start, you can follow the steps in the Amazon FSx for OpenZFS file system documentation page to create the file system, then, using the Amazon FSx console, go to Actions and select Create S3 access point. Leave the standard configuration and then create.

To monitor the creation progress, you can go to the Amazon FSx console.

Once available, choose the name of the new S3 access point and review the access point summary. This summary includes an automatically generated alias that works anywhere you would normally use S3 bucket names.

Using the bucket-style alias, you can access the FSx data directly through S3 API operations.

  • List objects using the ListObjectsV2 API

  • Get files using the GetObject API

  • Write data using the PutObject API

The data continues to be accessible via NFS.

Beyond accessing your FSx data through the S3 API, you can work with your data using the broad range of AI, ML, and analytics services that work with data in S3. For example, I built an Amazon Bedrock Knowledge Base using PDFs containing airline customer service information from my travel support application repository, WhatsApp-Powered RAG Travel Support Agent: Elevating Customer Experience with PostgreSQL Knowledge Retrieval, as the data source.

To create the Amazon Bedrock Knowledge Base, I followed the connection steps in Connect to Amazon S3 for your knowledge base user guide. I chose Amazon S3 as the data source, entered my S3 access point alias as the S3 source, then configured and created the knowledge base.

Once the knowledge base is synchronized, I can see all documents and the Document source as S3.

Finally, I ran queries against the knowledge base and verified that it successfully used the file data from my Amazon FSx for OpenZFS file system to provide contextual answers, demonstrating seamless integration without data movement.

Things to know
Integration and access control – Amazon S3 Access Points for Amazon FSx for OpenZFS file systems support standard S3 API operations (such as GetObject, ListObjectsV2, PutObject) through the S3 endpoint, with granular access controls through AWS Identity and Access Management (IAM) permissions and file system user authentication. Your S3 Access Point includes an automatically generated access point alias for data access using S3 bucket names, and public access is blocked by default for Amazon FSx resources.

Data management – Your data stays in your Amazon FSx for OpenZFS file system while becoming accessible as if it were in Amazon S3, eliminating the need for data movement or copies, with file data remaining accessible through NFS file protocols.

Performance – Amazon S3 Access Points for Amazon FSx for OpenZFS file systems deliver first-byte latency in the tens of milliseconds range, consistent with S3 bucket access. Performance scales with your Amazon FSx file system’s provisioned throughput, with maximum throughput determined by your underlying FSx file system configuration.

Pricing – You’re billed by Amazon S3 for the requests and data transfer costs through your S3 Access Point, in addition to your standard Amazon FSx charges. Learn more on the Amazon FSx for OpenZFS pricing page.

You can get started today using the Amazon FSx console, AWS CLI, or AWS SDK to attach Amazon S3 Access Points to your Amazon FSx for OpenZFS file systems. The feature is available in the following AWS Regions: US East (N. Virginia, Ohio), US West (Oregon), Europe (Frankfurt, Ireland, Stockholm), and Asia Pacific (Hong Kong, Singapore, Sydney, Tokyo).

— Eli

AWS Backup adds new Multi-party approval for logically air-gapped vaults

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-backup-adds-new-multi-party-approval-for-logically-air-gapped-vaults/

Today, we’re announcing the general availability of a new capability that integrates AWS Backup logically air-gapped vaults with Multi-party approval to provide access to your backups even when your AWS account is inaccessible due to inadvertent or malicious events. AWS Backup is a fully managed service that centralizes and automates data protection across AWS services and hybrid workloads. It provides core data protection features, ransomware recovery capabilities, and compliance insights and analytics for data protection policies and operations.

As a backup administrator, you use AWS Backup logically air-gapped vaults to securely share backups across accounts and organizations, logically isolate your backup storage, and support direct restore to help reduce recovery time following an inadvertent or malicious event. However, if a bad or unintended actor gains root access to your backup account or the management account of your organization, your backups suddenly become inaccessible, even though they’re still safely stored in the logically air-gapped vault. While traditional account recovery involved working through support channels, AWS Backup with Multi-party approval delivers immediate access to recovery tools, empowering you with faster resolution times and greater control over your recovery timeline.

Multi-party approval for AWS Backup logically air-gapped vaults adds an additional layer of protection for you to recover your application data even when your AWS account becomes completely inaccessible. Using Multi-party approval, you can create approval teams which consist of highly trusted individuals in your organization, then associate them with your logically air-gapped vault. If you get locked out of your AWS accounts due to inadvertent or malicious actions, you can request your own approval team to authorize sharing of your vault from any account, even those outside your AWS Organizations account. Once approved, you gain authorized access to your backups and can begin your recovery process.

How it works
Multi-party approval for AWS Backup logically air-gapped vaults combines the security of logically air-gapped vaults with the governance of Multi-party approval to create a recovery mechanism that works even when your AWS account is compromised. Here’s how it works:

1. Approval team creation
First, you create an approval team in your AWS Organizations management account. If the management account is new, first create an AWS Identity and Access Management (IAM) Identity Center instance before creating the approval team. The approval team consists of trusted individuals (IAM Identity Center users) who will be authorized to approve vault sharing requests. Each approver receives an invitation to join the approval team through a new Approval portal.

2. Vault association
When your approval team is active, you share it with accounts that own logically air-gapped vaults using AWS Resource Access Manager (AWS RAM) to safeguard against requests for approval from arbitrary accounts. Backup administrators can then associate this approval team with new or existing logically air-gapped vaults.

3. Protection against compromise
If your AWS account becomes compromised or inaccessible, you can request access to your backups from a different account (a clean recovery account). This request includes the Amazon Resource Name (ARN) of the logically air-gapped vault in the format arn:aws:backup:<region>:<account>:backup-vault:<name> and an optional vault name and comment.

4. Multi-party approval
The request is sent to the approval team, who review it through the approval portal. When the minimum required number of approvers authorize the request, the vault is automatically shared with the requesting account. All requests and approvals are comprehensively logged in AWS CloudTrail.

5. Recovery process
With access granted, you can immediately start restoring or copying your data in the new recovery account without waiting for your compromised account to be remediated.

This approach provides an entirely separate authentication path to access and recover your backups, completely independent of your AWS account credentials. Even if the bad actor has root access to your account, they can’t prevent the approval team-based recovery process.

1. Create a new logically air-gapped vault
To create a new logically air-gapped vault, provide a name, tags (optional), and vault lock properties.

2. Assign an approval team
When the vault has been created, choose Assign approval team to assign it with an existing approval team.

Choose an existing approval team from the drop-down menu then select Submit to finalize the assignment.

Now your approval team is assigned to your logically air-gapped vault.

Good to know
It’s essential to test your recovery process before an actual emergency:

  1. From a different AWS account, use the AWS Backup console or API to request sharing of your logically air-gapped vault by providing the vault ID and ARN.
  2. Request approval of your request from the approval team.
  3. Once approved, verify that you can access and restore backups from the vault in your testing account.

As a best practice, monitor the health of your approval team regularly using AWS Backup Audit Manager to ensure they have sufficient active participants to meet your approval threshold.

Multi-party approval for enhanced cloud governance
Today, we’re also announcing the general availability of a new capability that AWS account administrators can use to add Multi-party approval to their product offerings. As highlighted in this post, AWS Backup is the first service to integrate this capability. With Multi-party approval, administrators can enable application owners to guard sensitive service operations with a distributed review process.

Good to know
Multi-party approval provides several significant security advantages:

  • Distributed decision-making, eliminating single points of failure
  • Full auditability through AWS CloudTrail integration
  • Protection against compromised credentials
  • Formal governance for compliance-sensitive operations
  • Consistent approval experience across integrated services

Now available

Multi-party approval is available today in all AWS Regions where AWS Organizations is available. Multi-party approval for AWS Backup logically air-gapped vaults is available in all AWS Regions where AWS Backup is available.

– Veliswa.

Accelerate the transfer of data from an Amazon EBS snapshot to a new EBS volume

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/accelerate-the-transfer-of-data-from-an-amazon-ebs-snapshot-to-a-new-ebs-volume/

Today we are announcing the general availability of Amazon Elastic Block Store (Amazon EBS) Provisioned Rate for Volume Initialization, a feature that accelerates the transfer of data from an EBS snapshot, a highly durable backup of volumes stored in Amazon Simple Storage Service (Amazon S3) to a new EBS volume.

With Amazon EBS Provisioned Rate for Volume Initialization, you can create fully performant EBS volumes within a predictable amount of time. You can use this feature to speed up the initialization of hundreds of concurrent volumes and instances. You can also use this feature when you need to recover from an existing EBS Snapshot and need your EBS volume to be created and initialized as quickly as possible. You can use this feature to quickly create copies of EBS volumes with EBS Snapshots in a different Availability Zone, AWS Region, or AWS account. Provisioned Rate for Volume Initialization for each volume is charged based on the full snapshot size and the specified volume initialization rate.

This new feature expedites the volume initialization process by fetching the data from an EBS Snapshot to an EBS volume at a consistent rate that you specify between 100 MiB/s and 300 MiB/s. You can specify this volume initialization rate at which the snapshot blocks are to be downloaded from Amazon S3 to the volume.

With specifying the volume initialization rate, you can create a fully performant volume in a predictable time, enabling increased operational efficiency and visibility on the expected time of completion. If you run utilities like fio/dd to expedite volume initialization for your workflows like application recovery and volume copy for testing and development, it will remove the operational burden of managing such scripts with the consistency and predictability to your workflows.

Get started with specifying the volume initialization rate
To get started, you can choose the volume initialization rate when you launch your EC2 instance or create your volume from the snapshot.

1. Create a volume in the EC2 launch wizard
When launching new EC2 instances in the launch wizard of EC2 console, you can enter a desired Volume initialization rate in the Storage (volumes) section.

You can also set the volume initialization rate when creating and modifying the EC2 Launch Templates.

In the AWS Command Line Interface (AWS CLI), you can add VolumeInitializationRate parameter to the block device mappings when call run-instances command.

aws ec2 run-instances \
    --image-id ami-0abcdef1234567890 \
    --instance-type t2.micro \
    --subnet-id subnet-08fc749671b2d077c \
    --security-group-ids sg-0b0384b66d7d692f9 \
    --key-name MyKeyPair \
    --block-device-mappings file://mapping.json

Contents of mapping.json. This example adds /dev/sdh an empty EBS volume with a size of 8 GiB.

[
    {
        "DeviceName": "/dev/sdh",
        "Ebs": {
            "VolumeSize": 8
            "VolumeType": "gp3",            
            "VolumeInitializationRate": 300
		 } 
     } 
]

To learn more, visit block device mapping options, which defines the EBS volumes and instance store volumes to attach to the instance at launch.

2. Create a volume from snapshots
When you create a volume from snapshots, you can also choose Create volume in the EC2 console and specify the Volume initialization rate.

Confirm your new volume with the initialization rate.

In the AWS CLI, you can use VolumeInitializationRate parameter and when calling create-volume command.

aws ec2 create-volume --region us-east-1 --cli-input-json '{
    "AvailabilityZone": "us-east-1a",
    "VolumeType": "gp3",
    "SnapshotId": "snap-07f411eed12ef613a",
    "VolumeInitializationRate": 300
}'

If the command is run successfully, you will receive the result below.

{
    "AvailabilityZone": "us-east-1a",
    "CreateTime": "2025-01-03T21:44:53.000Z",
    "Encrypted": false,
    "Size": 100,
    "SnapshotId": "snap-07f411eed12ef613a",
    "State": "creating",
    "VolumeId": "vol-0ba4ed2a280fab5f9",
    "Iops": 300,
    "Tags": [],
    "VolumeType": "gp2",
    "MultiAttachEnabled": false,
    "VolumeInitializationRate": 300
}

You can also set the volume initialization rate when replacing root volumes of EC2 instances and provisioning EBS volumes using the EBS Container Storage Interface (CSI) driver.

After creation of the volume, EBS will keep track of the hydration progress and publish an Amazon EventBridge notification for EBS to your account when the hydration completes so that they can be certain when their volume is fully performant.

To learn more, visit Create an Amazon EBS volume and Initialize Amazon EBS volumes in the Amazon EBS User Guide.

Now available
Amazon EBS Provisioned Rate for Volume Initialization is now available and supported for all EBS volume types today. You will be charged based on the full snapshot size and the specified volume initialization rate. To learn more, visit Amazon EBS Pricing page.

To learn more about Amazon EBS including this feature, take the free digital course on the AWS Skill Builder portal. Course includes use cases, architecture diagrams and demos.

Give this feature a try in the Amazon EC2 console today and send feedback to AWS re:Post for Amazon EBS or through your usual AWS Support contacts.

— Channy


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)