[$] Moving past TCP in the data center, part 2

Post Syndicated from original https://lwn.net/Articles/914030/

At the end of our earlier article on John
Ousterhout’s talk at Netdev 0x16, he had concluded
that TCP was unsuitable for data-center environments for a variety of
reasons. He also argued that there was no way to repair TCP so that it
could serve the needs of data-center networking. In order for software to
be able
to use the full potential of today’s networking hardware, TCP needs to be
replaced with a protocol that is different in almost every way, he said.
The second
half of the talk covered the Homa
transport protocol
that he and others at Stanford have been working on
as a possible replacement for TCP in the data center.

Learn more about Apache Flink and Amazon Kinesis Data Analytics with three new videos

Post Syndicated from Deepthi Mohan original https://aws.amazon.com/blogs/big-data/learn-more-about-apache-flink-and-amazon-kinesis-data-analytics-with-three-new-videos/

Amazon Kinesis Data Analytics is a fully managed service for Apache Flink that reduces the complexity of building, managing, and integrating Apache Flink applications with other AWS services. Apache Flink is an open-source framework and engine for stateful processing of data streams. It’s highly available and scalable, delivering high throughput and low latency for the most demanding stream-processing applications.

In this post, we highlight three new videos for you to learn more about Apache Flink and Kinesis Data Analytics, including open-source contributions to Apache Flink, our learnings from running thousands of Flink jobs on a managed service, and how we use Kinesis Data Analytics and Apache Flink to enable machine learning (ML) in Alexa.

In Introducing the new Async Sink, we present the new Async Sink framework, an open-source contribution to make it easier than ever to build sink connectors for Apache Flink. You can learn about the need for the Async Sink framework and how we built it, followed by a demo of building a new sink to Amazon CloudWatch to deliver CloudWatch metrics, in under 20 minutes! The Async Sink framework bootstraps development of Flink sinks, is compatible with Apache Flink 1.15 and above, and has already seen usage by the community beyond building new sinks to AWS services.

The video Practical learnings from running thousands of Flink jobs shares insight from running Kinesis Data Analytics, a managed service for Apache Flink that runs tens of thousands of Flink jobs. You can learn lessons based on our experience of operating Apache Flink at very large scale, touching on issues such as out-of-memory errors, timeouts, and stability challenges. The video also covers improving application performance with memory tuning and configuration changes and the approaches to automating job health monitoring and management of Flink jobs at scale.

“Alexa, be quiet!” End-to-end near-real time model building and evaluation in Amazon Alexa discusses how Alexa has built an automated end-to-end solution for incremental model building or fine-tuning ML models through continuous learning, continual learning, or semi-supervised active learning. Alexa uses Apache Flink to transform and discover metrics in real time. In this video, you learn about how Alexa scales infrastructure to meet the needs of ML teams across Alexa, and explore specific use cases that use Apache Flink and Kinesis Data Analytics to improve Alexa experiences to delight customers.

To learn more about Kinesis Data Analytics for Apache Flink, visit our product page.


About the author

Deepthi Mohan is a Principal Product Manager on the Kinesis Data Analytics team.

Enrich VPC Flow Logs with resource tags and deliver data to Amazon S3 using Amazon Kinesis Data Firehose

Post Syndicated from Chaitanya Shah original https://aws.amazon.com/blogs/big-data/enrich-vpc-flow-logs-with-resource-tags-and-deliver-data-to-amazon-s3-using-amazon-kinesis-data-firehose/

VPC Flow Logs is an AWS feature that captures information about the network traffic flows going to and from network interfaces in Amazon Virtual Private Cloud (Amazon VPC). Visibility to the network traffic flows of your application can help you troubleshoot connectivity issues, architect your application and network for improved performance, and improve security of your application.

Each VPC flow log record contains the source and destination IP address fields for the traffic flows. The records also contain the Amazon Elastic Compute Cloud (Amazon EC2) instance ID that generated the traffic flow, which makes it easier to identify the EC2 instance and its associated VPC, subnet, and Availability Zone from where the traffic originated. However, when you have a large number of EC2 instances running in your environment, it may not be obvious where the traffic is coming from or going to simply based on the EC2 instance IDs or IP addresses contained in the VPC flow log records.

By enriching flow log records with additional metadata such as resource tags associated with the source and destination resources, you can more easily understand and analyze traffic patterns in your environment. For example, customers often tag their resources with resource names and project names. By enriching flow log records with resource tags, you can easily query and view flow log records based on an EC2 instance name, or identify all traffic for a certain project.

In addition, you can add resource context and metadata about the destination resource such as the destination EC2 instance ID and its associated VPC, subnet, and Availability Zone based on the destination IP in the flow logs. This way, you can easily query your flow logs to identify traffic crossing Availability Zones or VPCs.

In this post, you will learn how to enrich flow logs with tags associated with resources from VPC flow logs in a completely serverless model using Amazon Kinesis Data Firehose and the recently launched Amazon VPC IP Address Manager (IPAM), and also analyze and visualize the flow logs using Amazon Athena and Amazon QuickSight.

Solution overview

In this solution, you enable VPC flow logs and stream them to Kinesis Data Firehose. This solution enriches log records using an AWS Lambda function on Kinesis Data Firehose in a completely serverless manner. The Lambda function fetches resource tags for the instance ID. It also looks up the destination resource from the destination IP using the Amazon EC2 API and IPAM, and adds the associated VPC network context and metadata for the destination resource. It then stores the enriched log records in an Amazon Simple Storage Service (Amazon S3) bucket. After you have enriched your flow logs, you can query, view, and analyze them in a wide variety of services, such as AWS Glue, Athena, QuickSight, Amazon OpenSearch Service, as well as solutions from the AWS Partner Network such as Splunk and Datadog.

The following diagram illustrates the solution architecture.

Architecture

The workflow contains the following steps:

  1. Amazon VPC sends the VPC flow logs to the Kinesis Data Firehose delivery stream.
  2. The delivery stream uses a Lambda function to fetch resource tags for instance IDs from the flow log record and add it to the record. You can also fetch tags for the source and destination IP address and enrich the flow log record.
  3. When the Lambda function finishes processing all the records from the Kinesis Data Firehose buffer with enriched information like resource tags, Kinesis Data Firehose stores the result file in the destination S3 bucket. Any failed records that Kinesis Data Firehose couldn’t process are stored in the destination S3 bucket under the prefix you specify during delivery stream setup.
  4. All the logs for the delivery stream and Lambda function are stored in Amazon CloudWatch log groups.

Prerequisites

As a prerequisite, you need to create the target S3 bucket before creating the Kinesis Data Firehose delivery stream.

If using a Windows computer, you need PowerShell; if using a Mac, you need Terminal to run AWS Command Line Interface (AWS CLI) commands. To install the latest version of the AWS CLI, refer to Installing or updating the latest version of the AWS CLI.

Create a Lambda function

You can download the Lambda function code from the GitHub repo used in this solution. The example in this post assumes you are enabling all the available fields in the VPC flow logs. You can use it as is or customize per your needs. For example, if you intend to use the default fields when enabling the VPC flow logs, you need to modify the Lambda function with the respective fields. Creating this function creates an AWS Identity and Access Management (IAM) Lambda execution role.

To create your Lambda function, complete the following steps:

  1. On the Lambda console, choose Functions in the navigation pane.
  2. Choose Create function.
  3. Select Author from scratch.
  4. For Function name, enter a name.
  5. For Runtime, choose Python 3.8.
  6. For Architecture, select x86_64.
  7. For Execution role, select Create a new role with basic Lambda permissions.
  8. Choose Create function.

Create Lambda Function

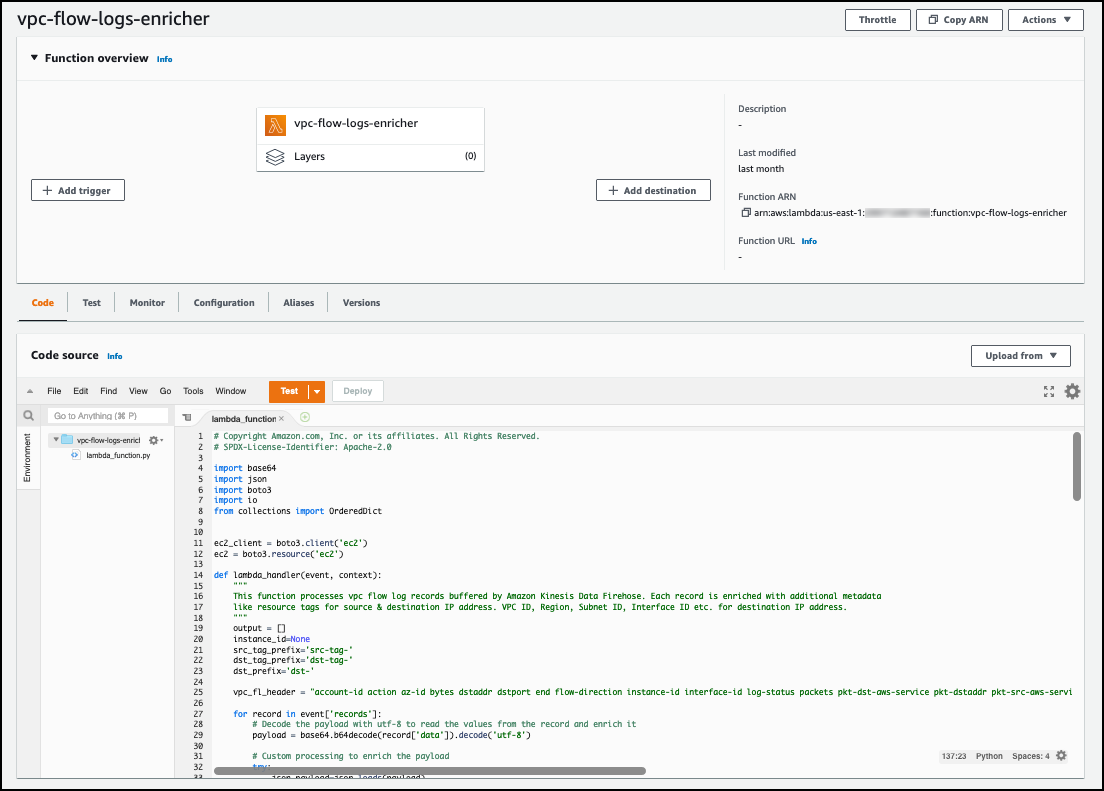
You can then see code source page, as shown in the following screenshot, with the default code in the lambda_function.py file.

  1. Delete the default code and enter the code from the GitHub Lambda function aws-vpc-flowlogs-enricher.py.
  2. Choose Deploy.

VPC Flow Logs Enricher function

To enrich the flow logs with additional tag information, you need to create an additional IAM policy to give Lambda permission to describe tags on resources from the VPC flow logs.

  1. On the IAM console, choose Policies in the navigation pane.
  2. Choose Create policy.
  3. On the JSON tab, enter the JSON code as shown in the following screenshot.

This policy gives the Lambda function permission to retrieve tags for the source and destination IP and retrieve the VPC ID, subnet ID, and other relevant metadata for the destination IP from your VPC flow log record.

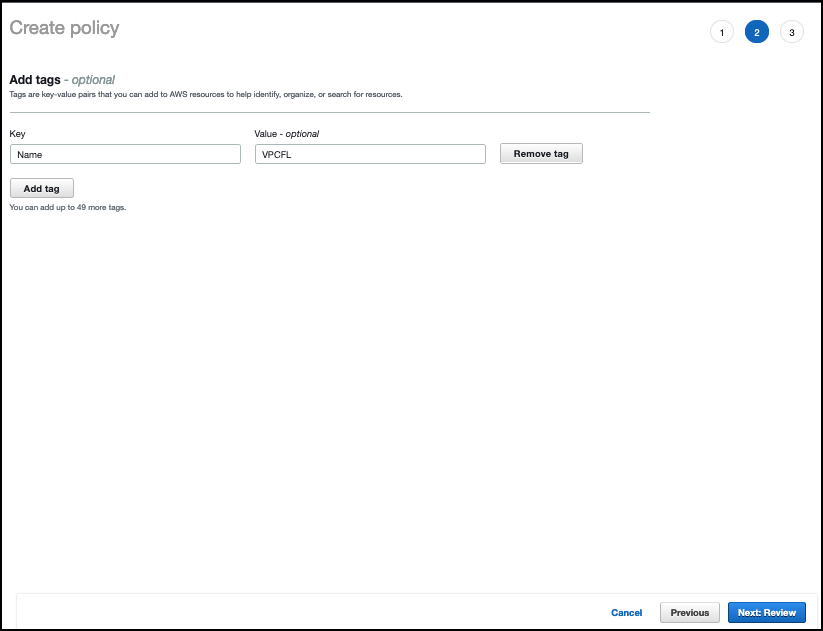
  1. Choose Next: Tags.

Tags

  1. Add any tags and choose Next: Review.

  1. For Name, enter vpcfl-describe-tag-policy.
  2. For Description, enter a description.
  3. Choose Create policy.

Create IAM Policy

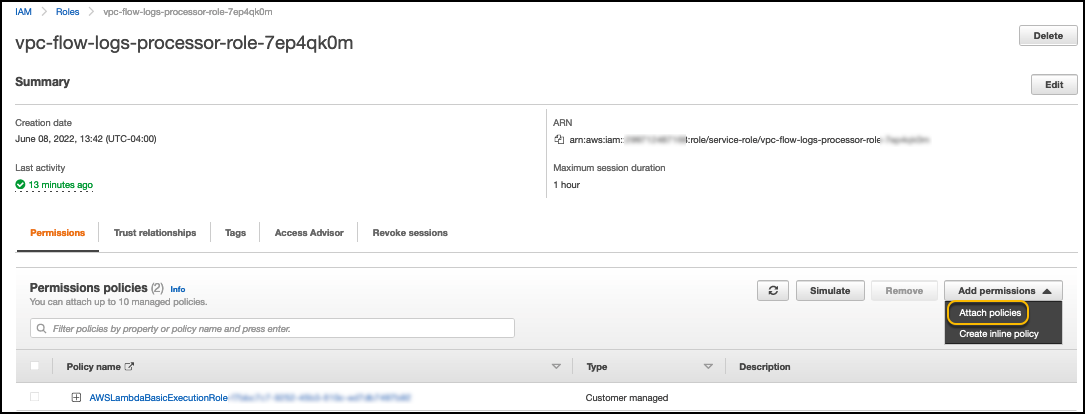
  1. Navigate to the previously created Lambda function and choose Permissions in the navigation pane.
  2. Choose the role that was created by Lambda function.

A page opens in a new tab.

  1. On the Add permissions menu, choose Attach policies.

Add Permissions

  1. Search for the vpcfl-describe-tag-policy you just created.
  2. Select the vpcfl-describe-tag-policy and choose Attach policies.

Create the Kinesis Data Firehose delivery stream

To create your delivery stream, complete the following steps:

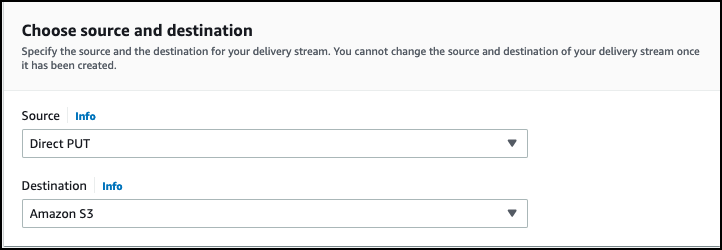
  1. On the Kinesis Data Firehose console, choose Create delivery stream.
  2. For Source, choose Direct PUT.
  3. For Destination, choose Amazon S3.

Kinesis Firehose Stream Source and Destination

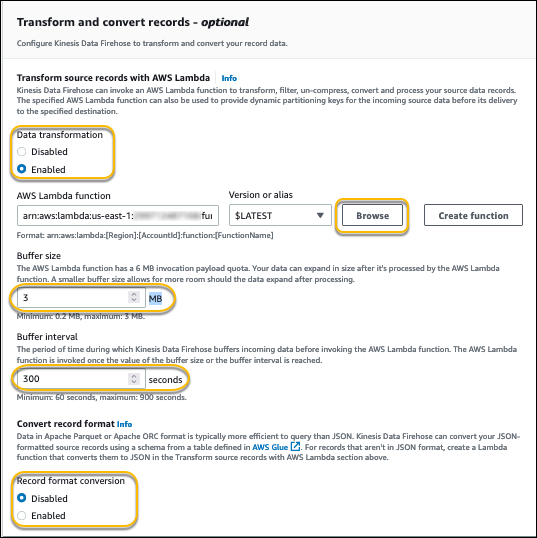
After you choose Amazon S3 for Destination, the Transform and convert records section appears.

  1. For Data transformation, select Enable.
  2. Browse and choose the Lambda function you created earlier.
  3. You can customize the buffer size as needed.

This impacts on how many records the delivery stream will buffer before it flushes it to Amazon S3.

  1. You can also customize the buffer interval as needed.

This impacts how long (in seconds) the delivery stream will buffer the incoming records from the VPC.

  1. Optionally, you can enable Record format conversion.

If you want to query from Athena, it’s recommended to convert it to Apache Parquet or ORC and compress the files with available compression algorithms, such as gzip and snappy. For more performance tips, refer to Top 10 Performance Tuning Tips for Amazon Athena. In this post, record format conversion is disabled.

Transform and Conver records

  1. For S3 bucket, choose Browse and choose the S3 bucket you created as a prerequisite to store the flow logs.
  2. Optionally, you can specify the S3 bucket prefix. The following expression creates a Hive-style partition for year, month, and day:

AWSLogs/year=!{timestamp:YYYY}/month=!{timestamp:MM}/day=!{timestamp:dd}/

  1. Optionally, you can enable dynamic partitioning.

Dynamic partitioning enables you to create targeted datasets by partitioning streaming S3 data based on partitioning keys. The right partitioning can help you to save costs related to the amount of data that is scanned by analytics services like Athena. For more information, see Kinesis Data Firehose now supports dynamic partitioning to Amazon S3.

Note that you can enable dynamic partitioning only when you create a new delivery stream. You can’t enable dynamic partitioning for an existing delivery stream.

Destination Settings

  1. Expand Buffer hints, compression and encryption.
  2. Set the buffer size to 128 and buffer interval to 900 for best performance.
  3. For Compression for data records, select GZIP.

S3 Buffer settings

Create a VPC flow log subscription

Now you create a VPC flow log subscription for the Kinesis Data Firehose delivery stream you created.

Navigate to AWS CloudShell or Terminal/PowerShell for a Mac or Windows computer and run the following AWS CLI command to enable the subscription. Provide your VPC ID for the parameter --resource-ids and delivery stream ARN for the parameter --log-destination.

aws ec2 create-flow-logs \ 
--resource-type VPC \ 
--resource-ids vpc-0000012345f123400d \ 
--traffic-type ALL \ 
--log-destination-type kinesis-data-firehose \ 
--log-destination arn:aws:firehose:us-east-1:123456789101:deliverystream/PUT-Kinesis-Demo-Stream \ 
--max-aggregation-interval 60 \ 
--log-format '${account-id} ${action} ${az-id} ${bytes} ${dstaddr} ${dstport} ${end} ${flow-direction} ${instance-id} ${interface-id} ${log-status} ${packets} ${pkt-dst-aws-service} ${pkt-dstaddr} ${pkt-src-aws-service} ${pkt-srcaddr} ${protocol} ${region} ${srcaddr} ${srcport} ${start} ${sublocation-id} ${sublocation-type} ${subnet-id} ${tcp-flags} ${traffic-path} ${type} ${version} ${vpc-id}'

If you’re running CloudShell for the first time, it will take a few seconds to prepare the environment to run.

After you successfully enable the subscription for your VPC flow logs, it takes a few minutes depending on the intervals mentioned in the setup to create the log record files in the destination S3 folder.

To view those files, navigate to the Amazon S3 console and choose the bucket storing the flow logs. You should see the compressed interval logs, as shown in the following screenshot.

S3 destination bucket

You can download any file from the destination S3 bucket on your computer. Then extract the gzip file and view it in your favorite text editor.

The following is a sample enriched flow log record, with the new fields in bold providing added context and metadata of the source and destination IP addresses:

{'account-id': '123456789101',
 'action': 'ACCEPT',
 'az-id': 'use1-az2',
 'bytes': '7251',
 'dstaddr': '10.10.10.10',
 'dstport': '52942',
 'end': '1661285182',
 'flow-direction': 'ingress',
 'instance-id': 'i-123456789',
 'interface-id': 'eni-0123a456b789d',
 'log-status': 'OK',
 'packets': '25',
 'pkt-dst-aws-service': '-',
 'pkt-dstaddr': '10.10.10.11',
 'pkt-src-aws-service': 'AMAZON',
 'pkt-srcaddr': '52.52.52.152',
 'protocol': '6',
 'region': 'us-east-1',
 'srcaddr': '52.52.52.152',
 'srcport': '443',
 'start': '1661285124',
 'sublocation-id': '-',
 'sublocation-type': '-',
 'subnet-id': 'subnet-01eb23eb4fe5c6bd7',
 'tcp-flags': '19',
 'traffic-path': '-',
 'type': 'IPv4',
 'version': '5',
 'vpc-id': 'vpc-0123a456b789d',
 'src-tag-Name': 'test-traffic-ec2-1', 'src-tag-project': ‘Log Analytics’, 'src-tag-team': 'Engineering', 'dst-tag-Name': 'test-traffic-ec2-1', 'dst-tag-project': ‘Log Analytics’, 'dst-tag-team': 'Engineering', 'dst-vpc-id': 'vpc-0bf974690f763100d', 'dst-az-id': 'us-east-1a', 'dst-subnet-id': 'subnet-01eb23eb4fe5c6bd7', 'dst-interface-id': 'eni-01eb23eb4fe5c6bd7', 'dst-instance-id': 'i-06be6f86af0353293'}

Create an Athena database and AWS Glue crawler

Now that you have enriched the VPC flow logs and stored them in Amazon S3, the next step is to create the Athena database and table to query the data. You first create an AWS Glue crawler to infer the schema from the log files in Amazon S3.

  1. On the AWS Glue console, choose Crawlers in the navigation pane.
  2. Choose Create crawler.

Glue Crawler

  1. For Name¸ enter a name for the crawler.
  2. For Description, enter an optional description.
  3. Choose Next.

Glue Crawler properties

  1. Choose Add a data source.
  2. For Data source¸ choose S3.
  3. For S3 path, provide the path of the flow logs bucket.
  4. Select Crawl all sub-folders.
  5. Choose Add an S3 data source.

Add Data source

  1. Choose Next.

Data source classifiers

  1. Choose Create new IAM role.
  2. Enter a role name.
  3. Choose Next.

Configure security settings

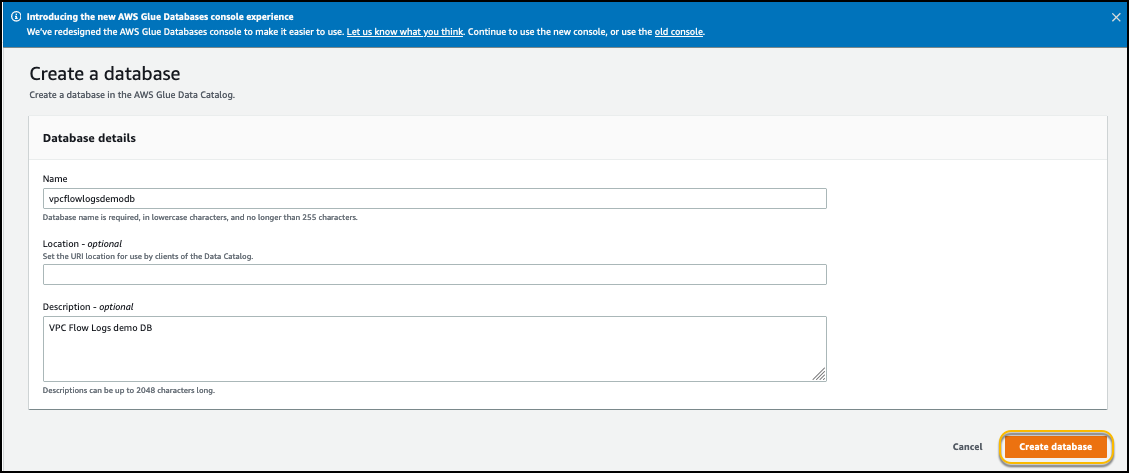
  1. Choose Add database.
  2. For Name, enter a database name.
  3. For Description, enter an optional description.
  4. Choose Create database.

Create Database

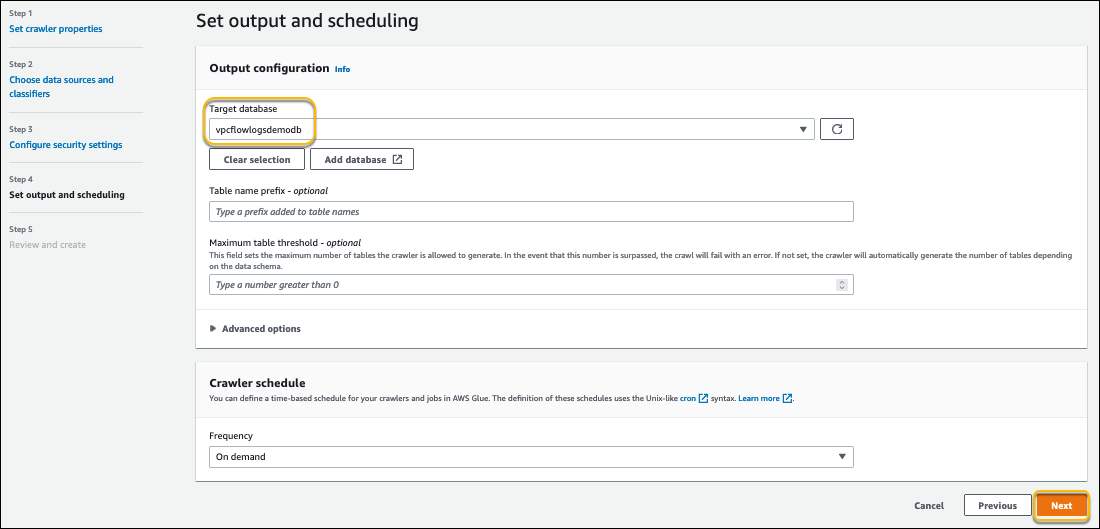
  1. On the previous tab for the AWS Glue crawler setup, for Target database, choose the newly created database.
  2. Choose Next.

Set output and scheduling

  1. Review the configuration and choose Create crawler.

Create crawler

  1. On the Crawlers page, select the crawler you created and choose Run.

Run crawler

You can rerun this crawler when new tags are added to your AWS resources, so that they’re available for you to query from the Athena database.

Run Athena queries

Now you’re ready to query the enriched VPC flow logs from Athena.

  1. On the Athena console, open the query editor.
  2. For Database, choose the database you created.
  3. Enter the query as shown in the following screenshot and choose Run.

Athena query

The following code shows some of the sample queries you can run:

Select * from awslogs where "dst-az-id"='us-east-1a'
Select * from awslogs where "src-tag-project"='Log Analytics' or "dst-tag-team"='Engineering' 
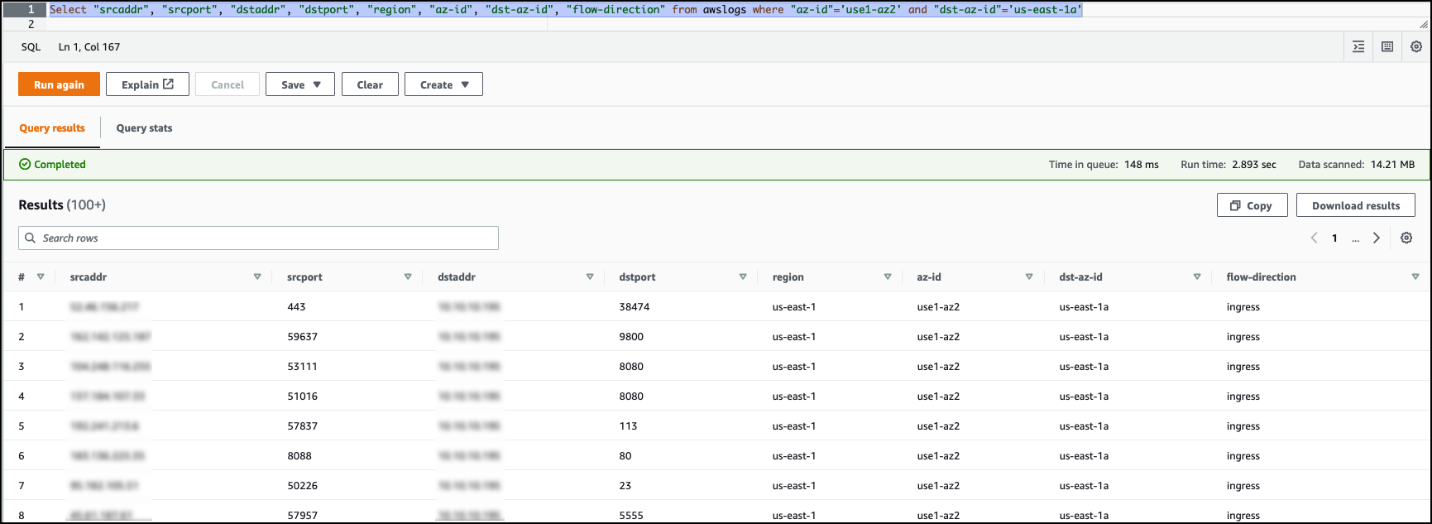
Select "srcaddr", "srcport", "dstaddr", "dstport", "region", "az-id", "dst-az-id", "flow-direction" from awslogs where "az-id"='use1-az2' and "dst-az-id"='us-east-1a'

The following screenshot shows an example query result of the source Availability Zone to the destination Availability Zone traffic.

Athena query result

You can also visualize various charts for the flow logs stored in the S3 bucket via QuickSight. For more information, refer to Analyzing VPC Flow Logs using Amazon Athena, and Amazon QuickSight.

Pricing

For pricing details, refer to Amazon Kinesis Data Firehose pricing.

Clean up

To clean up your resources, complete the following steps:

  1. Delete the Kinesis Data Firehose delivery stream and associated IAM role and policies.
  2. Delete the target S3 bucket.
  3. Delete the VPC flow log subscription.
  4. Delete the Lambda function and associated IAM role and policy.

Conclusion

This post provided a complete serverless solution architecture for enriching VPC flow log records with additional information like resource tags using a Kinesis Data Firehose delivery stream and Lambda function to process logs to enrich with metadata and store in a target S3 file. This solution can help you query, analyze, and visualize VPC flow logs with relevant application metadata because resource tags have been assigned to resources that are available in the logs. This meaningful information associated with each log record wherever the tags are available makes it easy to associate log information to your application.

We encourage you to follow the steps provided in this post to create a delivery stream, integrate with your VPC flow logs, and create a Lambda function to enrich the flow log records with additional metadata to more easily understand and analyze traffic patterns in your environment.


About the Authors

Chaitanya Shah is a Sr. Technical Account Manager with AWS, based out of New York. He has over 22 years of experience working with enterprise customers. He loves to code and actively contributes to AWS solutions labs to help customers solve complex problems. He provides guidance to AWS customers on best practices for their AWS Cloud migrations. He is also specialized in AWS data transfer and in the data and analytics domain.

Vaibhav Katkade is a Senior Product Manager in the Amazon VPC team. He is interested in areas of network security and cloud networking operations. Outside of work, he enjoys cooking and the outdoors.

Simplifying Amazon EC2 instance type flexibility with new attribute-based instance type selection features

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/simplifying-amazon-ec2-instance-type-flexibility-with-new-attribute-based-instance-type-selection-features/

This blog is written by Rajesh Kesaraju, Sr. Solution Architect, EC2-Flexible Compute and Peter Manastyrny, Sr. Product Manager, EC2.

Today AWS is adding two new attributes for the attribute-based instance type selection (ABS) feature to make it even easier to create and manage instance type flexible configurations on Amazon EC2. The new network bandwidth attribute allows customers to request instances based on the network requirements of their workload. The new allowed instance types attribute is useful for workloads that have some instance type flexibility but still need more granular control over which instance types to run on.

The two new attributes are supported in EC2 Auto Scaling Groups (ASG), EC2 Fleet, Spot Fleet, and Spot Placement Score.

Before exploring the new attributes in detail, let us review the core ABS capability.

ABS refresher

ABS lets you express your instance type requirements as a set of attributes, such as vCPU, memory, and storage when provisioning EC2 instances with ASG, EC2 Fleet, or Spot Fleet. Your requirements are translated by ABS to all matching EC2 instance types, simplifying the creation and maintenance of instance type flexible configurations. ABS identifies the instance types based on attributes that you set in ASG, EC2 Fleet, or Spot Fleet configurations. When Amazon EC2 releases new instance types, ABS will automatically consider them for provisioning if they match the selected attributes, removing the need to update configurations to include new instance types.

ABS helps you to shift from an infrastructure-first to an application-first paradigm. ABS is ideal for workloads that need generic compute resources and do not necessarily require the hardware differentiation that the Amazon EC2 instance type portfolio delivers. By defining a set of compute attributes instead of specific instance types, you allow ABS to always consider the broadest and newest set of instance types that qualify for your workload. When you use EC2 Spot Instances to optimize your costs and save up to 90% compared to On-Demand prices, instance type diversification is the key to access the highest amount of Spot capacity. ABS provides an easy way to configure and maintain instance type flexible configurations to run fault-tolerant workloads on Spot Instances.

We recommend ABS as the default compute provisioning method for instance type flexible workloads including containerized apps, microservices, web applications, big data, and CI/CD.

Now, let us dive deep on the two new attributes: network bandwidth and allowed instance types.

How network bandwidth attribute for ABS works

Network bandwidth attribute allows customers with network-sensitive workloads to specify their network bandwidth requirements for compute infrastructure. Some of the workloads that depend on network bandwidth include video streaming, networking appliances (e.g., firewalls), and data processing workloads that require faster inter-node communication and high-volume data handling.

The network bandwidth attribute uses the same min/max format as other ABS attributes (e.g., vCPU count or memory) that assume a numeric value or range (e.g., min: ‘10’ or min: ‘15’; max: ‘40’). Note that setting the minimum network bandwidth does not guarantee that your instance will achieve that network bandwidth. ABS will identify instance types that support the specified minimum bandwidth, but the actual bandwidth of your instance might go below the specified minimum at times.

Two important things to remember when using the network bandwidth attribute are:

  • ABS will only take burst bandwidth values into account when evaluating maximum values. When evaluating minimum values, only the baseline bandwidth will be considered.
    • For example, if you specify the minimum bandwidth as 10 Gbps, instances that have burst bandwidth of “up to 10 Gbps” will not be considered, as their baseline bandwidth is lower than the minimum requested value (e.g., m5.4xlarge is burstable up to 10 Gbps with a baseline bandwidth of 5 Gbps).
    • Alternatively, c5n.2xlarge, which is burstable up to 25 Gbps with a baseline bandwidth of 10 Gbps will be considered because its baseline bandwidth meets the minimum requested value.
  • Our recommendation is to only set a value for maximum network bandwidth if you have specific requirements to restrict instances with higher bandwidth. That would help to ensure that ABS considers the broadest possible set of instance types to choose from.

Using the network bandwidth attribute in ASG

In this example, let us look at a high-performance computing (HPC) workload or similar network bandwidth sensitive workload that requires a high volume of inter-node communications. We use ABS to select instances that have at minimum 10 Gpbs of network bandwidth and at least 32 vCPUs and 64 GiB of memory.

To get started, you can create or update an ASG or EC2 Fleet set up with ABS configuration and specify the network bandwidth attribute.

The following example shows an ABS configuration with network bandwidth attribute set to a minimum of 10 Gbps. In this example, we do not set a maximum limit for network bandwidth. This is done to remain flexible and avoid restricting available instance type choices that meet our minimum network bandwidth requirement.

Create the following configuration file and name it: my_asg_network_bandwidth_configuration.json

{
    "AutoScalingGroupName": "network-bandwidth-based-instances-asg",
    "DesiredCapacityType": "units",
    "MixedInstancesPolicy": {
        "LaunchTemplate": {
            "LaunchTemplateSpecification": {
                "LaunchTemplateName": "LaunchTemplate-x86",
                "Version": "$Latest"
            },
            "Overrides": [
                {
                "InstanceRequirements": {
                    "VCpuCount": {"Min": 32},
                    "MemoryMiB": {"Min": 65536},
                    "NetworkBandwidthGbps": {"Min": 10} }
                 }
            ]
        },
        "InstancesDistribution": {
            "OnDemandPercentageAboveBaseCapacity": 30,
            "SpotAllocationStrategy": "capacity-optimized"
        }
    },
    "MinSize": 1,
    "MaxSize": 10,
    "DesiredCapacity":10,
    "VPCZoneIdentifier": "subnet-f76e208a, subnet-f76e208b, subnet-f76e208c"
}

Next, let us create an ASG using the following command:

my_asg_network_bandwidth_configuration.json file

aws autoscaling create-auto-scaling-group --cli-input-json file://my_asg_network_bandwidth_configuration.json

As a result, you have created an ASG that may include instance types m5.8xlarge, m5.12xlarge, m5.16xlarge, m5n.8xlarge, and c5.9xlarge, among others. The actual selection at the time of the request is made by capacity optimized Spot allocation strategy. If EC2 releases an instance type in the future that would satisfy the attributes provided in the request, that instance will also be automatically considered for provisioning.

Considered Instances (not an exhaustive list)


Instance Type        Network Bandwidth
m5.8xlarge             “10 Gbps”

m5.12xlarge           “12 Gbps”

m5.16xlarge           “20 Gbps”

m5n.8xlarge          “25 Gbps”

c5.9xlarge               “10 Gbps”

c5.12xlarge             “12 Gbps”

c5.18xlarge             “25 Gbps”

c5n.9xlarge            “50 Gbps”

c5n.18xlarge          “100 Gbps”

…

Now let us focus our attention on another new attribute – allowed instance types.

How allowed instance types attribute works in ABS

As discussed earlier, ABS lets us provision compute infrastructure based on our application requirements instead of selecting specific EC2 instance types. Although this infrastructure agnostic approach is suitable for many workloads, some workloads, while having some instance type flexibility, still need to limit the selection to specific instance families, and/or generations due to reasons like licensing or compliance requirements, application performance benchmarking, and others. Furthermore, customers have asked us to provide the ability to restrict the auto-consideration of newly released instances types in their ABS configurations to meet their specific hardware qualification requirements before considering them for their workload. To provide this functionality, we added a new allowed instance types attribute to ABS.

The allowed instance types attribute allows ABS customers to narrow down the list of instance types that ABS considers for selection to a specific list of instances, families, or generations. It takes a comma separated list of specific instance types, instance families, and wildcard (*) patterns. Please note, that it does not use the full regular expression syntax.

For example, consider container-based web application that can only run on any 5th generation instances from compute optimized (c), general purpose (m), or memory optimized (r) families. It can be specified as “AllowedInstanceTypes”: [“c5*”, “m5*”,”r5*”].

Another example could be to limit the ABS selection to only memory-optimized instances for big data Spark workloads. It can be specified as “AllowedInstanceTypes”: [“r6*”, “r5*”, “r4*”].

Note that you cannot use both the existing exclude instance types and the new allowed instance types attributes together, because it would lead to a validation error.

Using allowed instance types attribute in ASG

Let us look at the InstanceRequirements section of an ASG configuration file for a sample web application. The AllowedInstanceTypes attribute is configured as [“c5.*”, “m5.*”,”c4.*”, “m4.*”] which means that ABS will limit the instance type consideration set to any instance from 4th and 5th generation of c or m families. Additional attributes are defined to a minimum of 4 vCPUs and 16 GiB RAM and allow both Intel and AMD processors.

Create the following configuration file and name it: my_asg_allow_instance_types_configuration.json

{
    "AutoScalingGroupName": "allow-instance-types-based-instances-asg",
    "DesiredCapacityType": "units",
    "MixedInstancesPolicy": {
        "LaunchTemplate": {
            "LaunchTemplateSpecification": {
                "LaunchTemplateName": "LaunchTemplate-x86",
                "Version": "$Latest"
            },
            "Overrides": [
                {
                "InstanceRequirements": {
                    "VCpuCount": {"Min": 4},
                    "MemoryMiB": {"Min": 16384},
                    "CpuManufacturers": ["intel","amd"],
                    "AllowedInstanceTypes": ["c5.*", "m5.*","c4.*", "m4.*"] }
            }
            ]
        },
        "InstancesDistribution": {
            "OnDemandPercentageAboveBaseCapacity": 30,
            "SpotAllocationStrategy": "capacity-optimized"
        }
    },
    "MinSize": 1,
    "MaxSize": 10,
    "DesiredCapacity":10,
    "VPCZoneIdentifier": "subnet-f76e208a, subnet-f76e208b, subnet-f76e208c"
}

As a result, you have created an ASG that may include instance types like m5.xlarge, m5.2xlarge, c5.xlarge, and c5.2xlarge, among others. The actual selection at the time of the request is made by capacity optimized Spot allocation strategy. Please note that if EC2 will in the future release a new instance type which will satisfy the other attributes provided in the request, but will not be a member of 4th or 5th generation of m or c families specified in the allowed instance types attribute, the instance type will not be considered for provisioning.

Selected Instances (not an exhaustive list)

m5.xlarge

m5.2xlarge

m5.4xlarge

…

c5.xlarge

c5.2xlarge

…

m4.xlarge

m4.2xlarge

m4.4xlarge

…

c4.xlarge

c4.2xlarge

…

As you can see, ABS considers a broad set of instance types for provisioning, however they all meet the compute attributes that are required for your workload.

Cleanup

To delete both ASGs and terminate all the instances, execute the following commands:

aws autoscaling delete-auto-scaling-group --auto-scaling-group-name network-bandwidth-based-instances-asg --force-delete

aws autoscaling delete-auto-scaling-group --auto-scaling-group-name allow-instance-types-based-instances-asg --force-delete

Conclusion

In this post, we explored the two new ABS attributes – network bandwidth and allowed instance types. Customers can use these attributes to select instances based on network bandwidth and to limit the set of instances that ABS selects from. The two new attributes, as well as the existing set of ABS attributes enable you to save time on creating and maintaining instance type flexible configurations and make it even easier to express the compute requirements of your workload.

ABS represents the paradigm shift in the way that our customers interact with compute, making it easier than ever to request diversified compute resources at scale. We recommend ABS as a tool to help you identify and access the largest amount of EC2 compute capacity for your instance type flexible workloads.

How Kyligence Cloud uses Amazon EMR Serverless to simplify OLAP

Post Syndicated from Daniel Gu original https://aws.amazon.com/blogs/big-data/how-kyligence-cloud-uses-amazon-emr-serverless-to-simplify-olap/

This post was co-written with Daniel Gu and Yolanda Wang, from Kyligence.

Today, more than ever, organizations realize that modern business runs on data—almost all our interactions with business are based on data, and organizations must use analytics to understand, plan, and improve their operations. That is where Online Analytical Processing (OLAP) comes in. OLAP is designed to manage and analyze big data, enabling organizations to use their data to extract business insights in multiple dimensions.

Kyligence Cloud OLAP solution offers an Intelligent OLAP Platform to simplify multi-dimensional analytics for cloud data lakes. In the past, Kyligence used to deploy and maintain its own Spark clusters based on Amazon Elastic Compute Cloud (Amazon EC2) to handle the multi-dimensional model pre-computing process that required users to build their monitoring and alerting systems to improve the observability and reliability of the Spark cluster. In this post, we present how Kyligence built and end-to-end Kyligence Cloud OLAP solution with Amazon EMR Serverless to simplify deployment and operations, reduce costs, and accelerate time-to-value over the data lake.

What is Amazon EMR Serverless?

Amazon EMR Serverless is a big data cloud platform for running large-scale distributed data processing jobs, and machine learning (ML) applications using open-source analytics frameworks like Apache Spark and Apache Hive. Amazon EMR Serverless makes it easy and cost-effective for data engineers and analysts to run applications without having to tune, operate, optimize, secure, or manage clusters.

What is OLAP?

OLAP is an approach to quickly answer analytics queries at high speeds on large volumes of data, providing capabilities for precomputation, sophisticated data modeling, and multi-dimensional analytics by rolling up large, sometimes separate datasets into a multi-dimensional database known as an OLAP Cube that enables “slicing and dicing” of data from different viewpoints for a streamlined query experience. Apache Kylin, Apache Druid, and ClickHouse are some of the popular OLAP tools.

Although OLAP tools have been successfully used in various industries, they still face many challenges:

  • Dependence on IT organizations – Traditional OLAP tools require complex infrastructure to run large-scale data computing. It requires a large team of IT professionals to operate and maintain this infrastructure, resulting in high costs.
  • Need for large compute resources – Traditional OLAP tools need huge amount of computing resources for processing, and transforming data through a series of specific steps toward a concrete goal. Lack of computational capabilities leads to longer response times, limits the amount of data that can be processed, and impedes the flexibility of the OLAP tool greatly . As a result, data analysts are often confined to narrow datasets, incapable of analyzing all the data freely.
  • Inefficient usage of resources in the cloud – When a large-scale data modeling calculation is performed in the cloud, the cost estimation tools estimate and deploy the corresponding computing resources. However, the utilization rate of resources is often not very high, resulting in inefficient usage of resources.

With OLAP integrated with Amazon EMR Serverless, OLAP tools can use Amazon EMR Serverless as a serverless computing resource pool to complete data processing jobs, which simplifies and enhances user experience.

Kyligence approach to OLAP using Amazon EMR Serverless

Kyligence is an AWS ISV partner that offers an Intelligent OLAP Platform to simplify multi-dimensional analytics for cloud data lakes. As a cloud-native OLAP platform, Kyligence Cloud now integrates with Amazon EMR Serverless to automatically provision Spark to run indexing and building jobs. This empowers you to use all the features and benefits of Kyligence’s OLAP with Amazon EMR Serverless.

Kyligence seamlessly connects to major AWS-native data sources including Amazon Simple Storage Service (Amazon S3), Amazon Redshift, and Amazon Relational Database Service (Amazon RDS) to get the most out of your data on AWS, building a comprehensive AWS big data solution. During data modeling, Kyligence uses Amazon S3 to store the pre-computed data, and serves it for high concurrency queries. Kyligence also seamlessly interfaces with popular business intelligence (BI) tools such as Tableau, Microsoft Power BI, and Microsoft Excel to provide rich, built-in data visualization and self-service tools.

The following diagram illustrates the Kyligence Cloud architecture on AWS.

What you can expect from Kyligence Cloud on AWS

This solution offers the following benefits:

  • High performance – With AWS’s global infrastructure and the distributed computing capabilities of Amazon EMR, Kyligence offers a scalable, cost-effective, high-performance OLAP engine for multi-dimensional analytics. It enables critical data applications and large-scale interactive analytics, and helps you achieve sub-second query response times and high concurrency on PB-scale data.
  • Auto-scaling – Kyligence Cloud’s computing resources can be expanded with one click, and as load decreases, cluster size can be automatically reduced. This auto-scaling capability provides optimized costs with service stability.
  • High compatibility – Kyligence Cloud provides a rich set of APIs (ODBC, JDBC, Rest API, Python Client) and standard ANSI-SQL and XMLA/MDX interface, which can be easily integrated with popular analytics tools like Tableau, Microsoft Excel, Microsoft Power BI, and data science tools like Python.
  • Security and reliability – With Amazon S3, Amazon RDS, Kyligence enterprise-level security features, and AWS Identity and Access Management (IAM) support, Kyligence Cloud safely manages access to the services and resources deployed on AWS while supporting multi-level access control of data models, tables, and cells to ensure data security and privacy protection.
  • One-click deployment on AWS – Kyligence Cloud is available in AWS Marketplace. The deployment is completed automatically based on an AWS CloudFormation template and parameter settings. Kyligence performs automated cluster operation and maintenance, and elastic rule-based cluster scaling, which lightens the workload for IT administrators and cloud infrastructure teams. Kyligence also offers a quick deployment method in the Kyligence Cloud Portal.

How Amazon EMR Serverless integrates with OLAP

With Amazon EMR Serverless, Kyligence Cloud provides out-of-the-box managed Apache Spark services. The Kyligence engine can distribute the compute job to Apache Spark in Amazon EMR Serverless. With the automatic on-demand provisioning and scaling capabilities of Amazon EMR Serverless, Kyligence can quickly meet changing processing requirements at any data volume.

The following diagram illustrates Kyligence Cloud integrated with Amazon EMR Serverless.

Benefits of using Kyligence Cloud with Amazon EMR Serverless

In the past, Kyligence used to deploy and maintain its own Spark clusters based on Amazon Elastic Compute Cloud (Amazon EC2) to handle the multi-dimensional model pre-computing process that required Kyligence users to build their monitoring and alerting systems to improve the observability and reliability of the Spark clusters.

Now, running Kyligence on Amazon EMR Serverless offers a more cost-effective, and high-performance way to run cloud analytics on AWS:

  • Simplified deployment on the cloud – With managed services, you don’t need to consider the lifecycle of the underlying infrastructure and resources. This greatly reduces application complexity and simplifies the deployment of Kyligence Cloud.
  • Improve performance on the cloud – With the help of Amazon EMR Serverless, it provides a refined scaling strategy, which can help Kyligence Cloud spin up and recycle resources faster. In Kyligence performance benchmark testing, we observed 15–20% faster performance compared to open-source Spark cluster for index building.
  • Reduce the difficulty of operation and maintenance – With the help of Amazon EMR Serverless capabilities, operation and maintenance personnel can easily maintain the capacity and running status of computing resources without having to understand the underlying analysis framework.
  • Cost-optimization on the cloud – Amazon EMR Serverless provides a refined scaling strategy that can automatically determine the resources that the application needs, acquires these resources to process your jobs, and releases the resources when the jobs complete. You only pay for the resources used by the application, which helps reduce the Total Cost of Operations (TCO) on the cloud.

Get started with Kyligence Cloud on Amazon EMR Serverless

You can get started with the full potential of Kyligence Cloud on the AWS Marketplace or quickly test drive Kyligence.

To use Amazon EMR Serverless, you just need to select Serverless Spark on the Build Cluster tab during deployment.

Conclusion

Using managed and scalable services like Amazon EMR Serverless allows Kyligence users to speed up self-service analytics on large volumes of data, and maintain a relatively simplified architecture. With this solution, you can now concentrate on business demands instead of technical issues.

About Kyligence

Kyligence was founded in 2016 by the original creators of Apache Kylin™, the leading open-source OLAP for big data. Kyligence offers an Intelligent OLAP Platform to simplify multi-dimensional analytics for cloud data lakes.

For more information, visit Kyligence.


About the authors

Daniel Gu is a senior product manager on the Kyligence Cloud Team, who manages products and services and conducts research to determine the viability of products in the cloud.

Yolanda Wang is a senior product marketing manager at Kyligence, who owns the positioning, messaging, and branding of Kyligence products and works with various teams to drive go-to-market strategies.

Kiran Guduguntla is a WW Go-to-Market Specialist for Amazon EMR at AWS. He works with AWS customers across the globe to strategize, build, develop, and deploy modern data analytics solutions.

Protecting election groups during the 2022 US midterm elections

Post Syndicated from Andie Goodwin original https://blog.cloudflare.com/protecting-election-groups-during-the-2022-us-midterm-elections/

Protecting election groups during the 2022 US midterm elections

Protecting election groups during the 2022 US midterm elections

On Tuesday, November 8, 2022, constituents cast their ballots for the 2022 US midterm elections, which included races for all 435 seats in the House of Representatives, 35 of the 100 seats in the Senate, and many gubernatorial races in states including Florida, Michigan, and Pennsylvania. Preparing for elections is a giant task, and states and localities have their work cut out for them with corralling poll workers, setting up polling places, and managing the physical security of ballots and voting machines.

We at Cloudflare are proud to be able to play a role in helping safeguard the integrity of the electoral process. Through our Impact programs, we provide cyber security products to help protect access to authoritative voting information and the security of sensitive voter data.

We have reported on our work in the election space with the Athenian Project, dedicated to protecting state and local governments that run elections; Cloudflare for Campaigns, a project with a suite of Cloudflare products to secure political campaigns’ and state parties’ websites and internal teams; and Project Galileo, in which we have helped voting rights organizations and election results sites stay online during traffic spikes.

Since our reporting in 2020, we have expanded our relationships with government agencies and worked with project participants across the United States in a range of election roles to support free and fair elections. For the midterm elections, we continued to support election entities with the tools and expertise on how to secure their web infrastructure to promote trust in the voting process.

Overall, we were ready for the unexpected, as we had experience supporting those in the election community in 2020 during a time of uncertainty around COVID-19 and increased political polarization. But for the midterms, the Cybersecurity and Infrastructure Security Agency (CISA), the key agency tasked with protecting election infrastructure against cyber threats, reported the morning of November 8 that they “continue to see no specific or credible threat to disrupt election infrastructure” for the day of the election.

At Cloudflare, although we did see reports of a few smaller attacks and outages, we are pleased that the robust cyber security preparations by governments, nonprofits, local municipalities, campaigns, and state parties appeared to be successful, as we did not identify large-scale attacks on November 8, 2022.

Below are highlights on the activity we saw as we approached midterms and how we worked together with all of these groups to secure election resources.

Key takeaways from the 2022 midterm elections

For state and local governments protected under the Athenian Project

  • We protect 361 election websites in 31 states. This is a 31% increase since our reporting during the 2020 election.
  • Average daily application-layer attack volume against Athenian sites was only 3.4% higher in November through Election Day than it was in October.
  • From October 1 through November 8, 2022, government election sites experienced an average of 16,170,728 threats per day.
  • A majority of the threats to government election sites that Cloudflare mitigated in October 2022 were classified as HTTP anomaly, SQL injection, and software specific CVEs.

For political campaigns and state parties protected under Cloudflare for Campaigns

  • With our partnership with Defending Digital Campaigns, we protected 56 House campaigns, 15 political parties, and 34 Senate campaigns during the midterm elections.
  • Average daily application-layer attack volume against campaign sites was over 3x higher in November through Election Day than it was in October.
  • From October 1 through November 8, 2022, political campaign and state party sites saw an average of 149,949 threats per day.
  • HTTP anomaly, SQL injection, and directory traversal were the most active categories for mitigated requests against campaign sites in October.

Risks to online election groups as we approached the midterms

In preparation for the midterms, the Federal Bureau of Investigation (FBI) and CISA put out a variety of public service announcements calling attention to cyber election risks, like DDoS attacks, and providing reassurance that cyber attacks were “unlikely to result in large-scale disruptions or prevent voting.” Earlier this year, the FBI issued a warning on phishing attempts, with details about a seemingly organized plot to steal election officials’ credentials via an email with a fake invoice attached.

We also saw some threat actors announce plans to target the midterm elections. Killnet, a pro-Russia hacking group, targeted US state websites, successfully taking the public-facing websites of a number of states temporarily offline. Hacking groups will target public-facing government websites to promote mistrust in the democratic process.

Voting authorities face challenges unrelated to malicious activity, too. Without the proper tools in place, traffic spikes during election season can impede voters’ ability to access information about polling places, registration, and results. During the 2020 US election, we saw 4x traffic spikes to government elections sites.

On the political organizing side, political campaigns and state parties increasingly rely on the Internet and their web presence to issue policy stances, raise donations, and organize their campaign operations. In October 2022, the FBI notified Republican and Democratic state parties that Chinese hackers were scanning party websites for vulnerabilities.

So, what happened during the 2022 US midterm elections?

Protecting election groups during the 2022 US midterm elections

As we prepared for the midterms, we had a team of engineers ready to assist state and local governments, campaigns, political parties, and voting rights organizations looking for help to protect their websites from cyber attacks. A majority of the threats that we saw and directly assisted on were before the election, especially in the wake of many advisories from federal agencies on Killnet’s targeting of US government sites.

During this time, we worked with CISA’s Joint Cyber Defense Collaborative (JCDC) to provide security briefings to state and local election officials and to make sure our free Enterprise services for state and local governments under the Athenian Project were part of JCDC’s Cybersecurity Toolkit to Protect Elections. We provided additional support in terms of webinars, security recommendations, and best practices to better prepare these groups for the midterms.

A week before the election, we worked with partners such as Defending Digital Campaigns to onboard many political campaigns and state parties to Cloudflare for Campaigns after seeing a number of campaigns come under DDoS attack. With this, we were able to accept 21 of the Senate Campaigns up for re-election, with an overall total of 34 Senate campaigns protected under the project.

Preparing for the next election

Being in the election space means working with local government, campaigns, state parties, and voting rights organizations to build trust. Democracies rely on access to information and trusted election results.

We accept applications to the Athenian Project all year long, not just during election season — learn how to apply. We look forward to providing more information on threats to these actors in the election space in the next few months to support their valuable work.

New Research: Optimizing DAST Vulnerability Triage with Deep Learning

Post Syndicated from Tom Caiazza original https://blog.rapid7.com/2022/11/09/new-research-optimizing-dast-vulnerability-triage-with-deep-learning/

New Research: Optimizing DAST Vulnerability Triage with Deep Learning

On November 11th 2022, Rapid7 will for the first time publish and present state-of-the-art machine learning (ML) research at AISec, the leading venue for AI/ML cybersecurity innovations. Led by Dr. Stuart Millar, Senior Data Scientist, Rapid7’s multi-disciplinary ML group has designed a novel deep learning model to automatically prioritize application security vulnerabilities and reduce false positive friction. Partnering with The Centre for Secure Information Technologies (CSIT) at Queen’s University Belfast, this is the first deep learning system to optimize DAST vulnerability triage in application security. CSIT is the UK’s Innovation and Knowledge Centre for cybersecurity, recognised by GCHQ and EPSRC as a Centre of Excellence for cybersecurity research.

Security teams struggle tremendously with prioritizing risk and managing a high level of false positive alerts, while the rise of the cloud post-Covid means web application security is more crucial than ever. Web attacks continue to be the most common type of compromise; however, high levels of false positives generated by vulnerability scanners have become an industry-wide challenge. To combat this, Rapid7’s innovative ML architecture optimizes vulnerability triage by utilizing the structure of traffic exchanges between a DAST scanner and a given web application. Leveraging convolutional neural networks and natural language processing, we designed a deep learning system that encapsulates internal representations of request and response HTTP traffic before fusing them together to make a prediction of a verified vulnerability or a false positive. This system learns from historical triage carried out by our industry-leading SMEs in Rapid7’s Managed Services division.

Given the skillset, time, and cognitive effort required to review high volumes of DAST results by hand, the addition of this deep learning capability to a scanner creates a hybrid system that enables application security analysts to rank scan results, deprioritise false positives, and concentrate on likely real vulnerabilities. With the system able to make hundreds of predictions per second, productivity is improved and remediation time reduced, resulting in stronger customer security postures. A rigorous evaluation of this machine learning architecture across multiple customers shows that 96% of false positives on average can automatically be detected and filtered out.

Rapid7’s deep learning model uses convolutional neural networks and natural language processing to represent the structure of client-server web traffic. Neither the model nor the scanner require source code access — with this hybrid approach first finding potential vulnerabilities using a scan engine, followed by the model predicting those findings as real vulnerabilities or false positives. The resultant solution enables the augmentation of triage decisions by deprioritizing false positives. These time savings are essential to reduce exposure and harden security postures — considering the average time to detect a web breach can be several months, the sooner a vulnerability can be discovered, verified and remediated, the smaller the window of opportunity for an attacker.

Now recognized as state-of-the-art research after expert peer review, Rapid7 will introduce the work at AISec on Nov 11th 2022 at the Omni Los Angeles Hotel at California Plaza. Watch this space for further developments, and download a copy of the pre-print publication here.

New MITRE Engenuity ATT&CK® Evaluation: Rapid7 MDR Excels

Post Syndicated from Warwick Webb original https://blog.rapid7.com/2022/11/09/new-mitre-engenuity-att-ck-r-evaluation-rapid7-mdr-excels/

New MITRE Engenuity ATT&CK® Evaluation: Rapid7 MDR Excels

Every Managed Services organization claims they have the expertise and technology to effectively detect and respond to threats. But can they prove it?

Assessing these services and how they’d perform in a real-world scenario just got easier with results from the first ever MITRE ATT&CK Evaluations for Managed Services.

Rapid7 MDR was excited to participate in this inaugural evaluation, along with 16 other Managed Service providers. We battle adversaries on behalf of our customers every single day, but most of this work goes largely unseen. This evaluation was an opportunity to show a wider audience the early detection, accelerated action, and deep partnership engagement that Rapid7 MDR delivers to customers across the globe every day.

And the results speak for themselves.

Rapid7 reported malicious activity across all 10 ATT&CK Evaluation steps

Rapid7 MDR reported 63 of the 74 total attacker ‘techniques’ within these steps, accurately describing the full scope and impact of the breach while maintaining the strong signal-to-noise ratio that everyone expects of Rapid7.

This evaluation offers visibility into a real-world engagement with Rapid7. What our team delivered to MITRE Engenuity wasn’t ‘special’ treatment, but rather a demonstration of the resources, experience, and technology we bring to bear for all customers as part of the unlimited incident response service included with Rapid7 MDR.

Here are other highlights:

Reliable, early detection: we stopped OilRig (a.k.a. APT34) at the starting line

The attack began in a familiar way: a phishing email was used to drop a malicious payload and establish persistence on the workstation of an unsuspecting user. With a foothold in the environment, the attacker performed discovery actions and dumped user credentials, before moving laterally across the organization and eventually collecting and exfiltrating sensitive data.

Rapid7 MDR identified the very first step in the attack, notifying MITRE about the download and execution of the initial malicious payload and providing recommended actions to contain the threat. Had this been a ‘real world’ customer incident, the attack would have stopped here.

Comprehensive coverage across kill chain

As the attack was allowed to continue, our team went on to identify and report to MITRE Engenuity all major steps of the compromise – from discovery and credential dumping to Web shell installation, data staging, data exfiltration, and cleanup.

Robust, actionable reporting

The evaluation also highlights the comprehensive reporting, robust communications, detailed timelines, and deep forensic investigation that Rapid7 MDR customers receive. At the conclusion of the engagement, we delivered a comprehensive 40 page incident report describing in detail the full scope and impact of the breach and attributed the activity to APT group OilRig, an Iran-linked hacking group known to target critical infrastructure.

MDR left the environment better than we found it

While containment was out of scope for this evaluation, you’ll see that Rapid7 provided detailed response and mitigation recommendations along the way. While other Managed Services put work back on the customer to figure out how to resolve incidents and harden their security to prevent similar incidents in the future, Rapid7 provides this guidance and partners with customers to ensure these recommendations are implemented. We provide an end-to-end detection and response program.

Finally, what the MITRE ATT&CK Evaluation doesn’t show you

What’s reported out here is just a slice of what’s possible with Rapid7 MDR.

While this evaluation was largely endpoint-focused, our customers get complete coverage: endpoints, network, users, cloud, and more. As the attack surface grows in complexity, you need a real MDR partner, scaling with your business, driving the end-to-end results, staying ahead of the most advanced attacks, working as a seamless extension of your team.

Our many differences, including integrated DFIR, add up.

To learn more about our evaluation, join our webcast.

Security updates for Wednesday

Post Syndicated from original https://lwn.net/Articles/914221/

Security updates have been issued by Debian (vim, webkit2gtk, and wpewebkit), Fedora (mingw-python3, vim, webkit2gtk3, webkitgtk, and xen), Mageia (389-ds-base, bluez, ffmpeg, libtasn1, libtiff, libxml2, and mbedtls), Red Hat (kpatch-patch and linux-firmware), SUSE (conmon, containerized data importer, exim, expat, ganglia-web, gstreamer-0_10-plugins-base, gstreamer-0_10-plugins-good, gstreamer-plugins-base, gstreamer-plugins-good, kernel, kubevirt, protobuf, sendmail, and vsftpd), and Ubuntu (libzstd, openjdk-8, openjdk-lts, openjdk-17, openjdk-19, php7.2, php7.4, php8.1, and pixman).

Accelerating Well-Architected Framework reviews using integrated AWS Trusted Advisor insights

Post Syndicated from Stephen Salim original https://aws.amazon.com/blogs/architecture/accelerating-well-architected-framework-reviews-using-integrated-aws-trusted-advisor-insights/

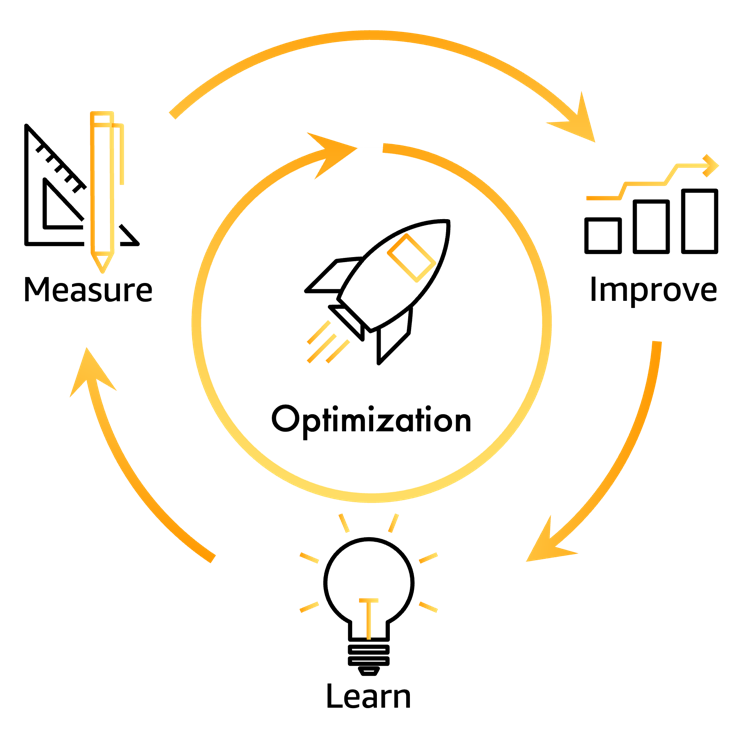
In this blog, we will explain how the new AWS Well-Architected integration with AWS Trusted Advisor can give you insights that help you create a flywheel effect to accelerate your cloud optimization. Customers that have the most success in their cloud adoption recognize that optimizing their cloud architecture and operations is not a one-time effort. Optimization is a continuous improvement virtuous cycle based on learning architectural and operational best practices, measuring workloads against these best practices, and implementing improvements based on opportunities recognized from measurement.

Customers can use the AWS Well-Architected Framework to build a “learn, measure, and improve” continuous improvement virtuous cycle (Figure 1). With the AWS Well-Architected Tool, customers can measure their workloads against these AWS best practices to identify improvement opportunities or risks they should address. After customers complete Well-Architected Framework Reviews (WAFRs) they can generate improvement plans with prioritized guidance and resources for improvement. They can also track the improvements made over time using the milestones feature in the Well-Architected Tool.

Continuous optimization of workloads based on AWS best practices

Figure 1. Continuous optimization of workloads based on AWS best practices

Amazon uses the term flywheel to describe a virtuous cycle that has additional drivers to add momentum, which accelerates the cycle and the value it delivers. Figure 2 is the often-referenced Amazon retail flywheel, which shows how Amazon’s focus on customer experience drives growth. It is accelerated by creating a lower cost structure, which allows Amazon to pass lower prices to its customers, improving customer experience and driving faster growth.

Amazon Flywheel concept of scaling growth

Figure 2. The Amazon Flywheel concept of scaling growth

Customers can add momentum to an AWS Well-Architected “learn, measure, and improve” virtuous cycle using tools that give more insights while measuring workloads. Improved insights result in consistent measurements, that are more efficient and more accurate. This accelerates the optimization cycle by reducing the time required to measure workloads. Collecting information on AWS resources using Trusted Advisor checks allows customers to validate if a workload’s state is aligned with AWS best practices. The new AWS Well-Architected Tool integration with AWS Trusted Advisor makes it easier and faster to gain insights during WAFRs. The Trusted Advisor checks that are relevant to a specific set of best practices have been mapped to the corresponding questions in Well-Architected. The new feature now shows the mapped Trusted Advisor checks directly in the Well-Architected Tool. These insights help customers run WAFRs in less time, with more accuracy, creating a flywheel effect (Figure 3).

Insights from AWS Trusted Advisor create acceleration in achieving improved outcomes

Figure 3. Insights from AWS Trusted Advisor create acceleration in achieving improved outcomes

AWS Well-Architected Tool integration with AWS Trusted Advisor: feature example

In the following sections, we detail an example scenario on how to use the integration with Trusted Advisor to gain insights when measuring your workloads.

Enabling the AWS Well-Architected Tool integration with AWS Trusted Advisor

How to enable the new feature in your workload:

  1. Create a new workload in the AWS Well-Architected Console. Refer to the user guide for detailed instructions.

    Optional
    : When defining a workload, within the “Application” section of workload definition, you can now also specify the AWS Service Catalog AppRegistry AWS Resource Name (ARN). This field is to indicate a relationship between the AWS Well-Architected Tool workload and the AWS resources in an AppRegistry Application when performing a Well-Architected Framework Review (Figure 4).

    Application field to select AWS Service Catalog AppRegistry ARN

    Figure 4. Application field to select AWS Service Catalog AppRegistry ARN

    This is another new AWS Well-Architected Tool feature that launched along with the integration with Trusted Advisor feature. You can find out more details about the integration with AWS Service Catalog AppRegistry in the What’s New post and on the feature documentation page. For details on how to create an AWS Service Catalog AppRegistry Application refer to Creating applications.

  2. To enable the integration with Trusted Advisor, after the necessary workload information has been entered, within the “AWS Trusted Advisor” section, tick on “Activate Trusted Advisor” (Figure 5).
    Enabling the Trusted Advisor feature

    Figure 5. Enabling the AWS Trusted Advisor feature

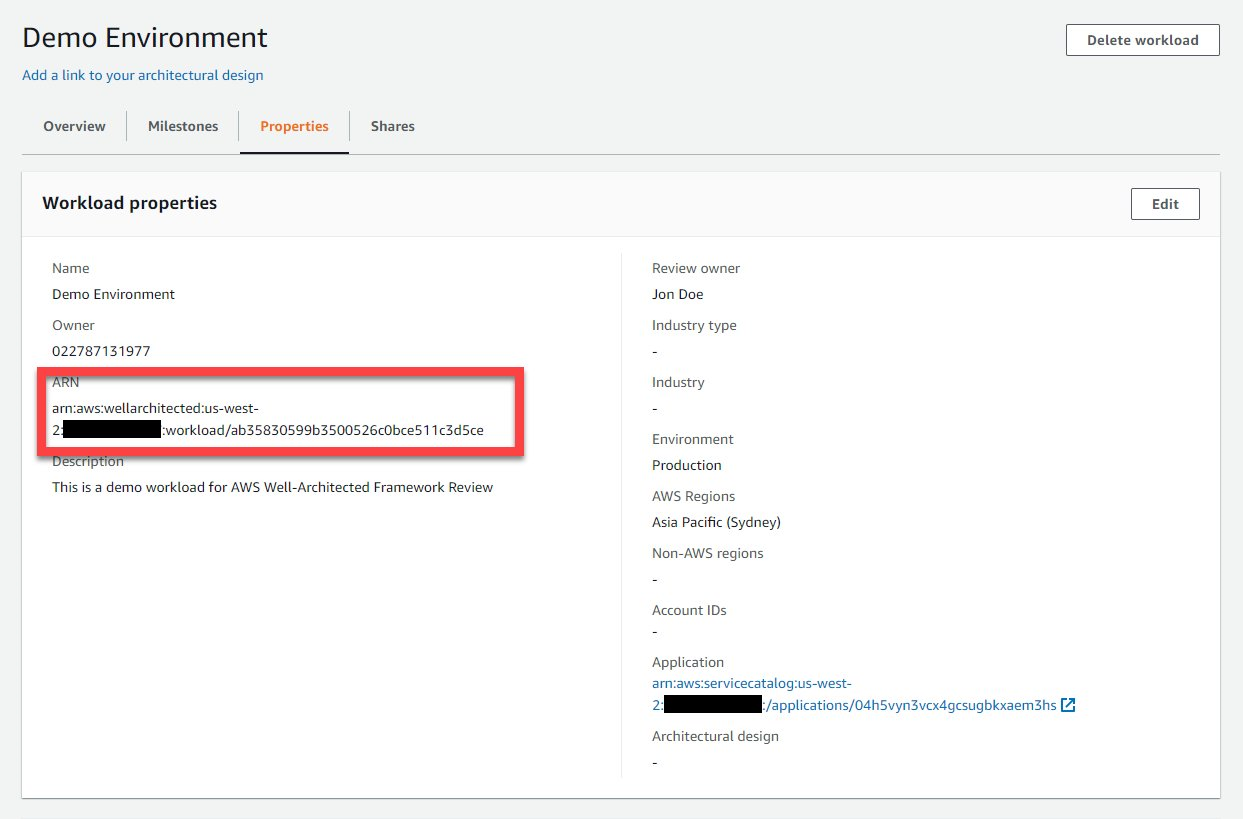
    Optional: Once the workload is created, note the workload ARN. You can find the workload ARN in the Properties section of the workload resource you created (Figure 6). For steps on how to identify your workload, refer to Well-Architected Tool User Guide on viewing a workload.

    AWS Well-Architected Tool showing workload ARN

    Figure 6. AWS Well-Architected Tool showing workload ARN

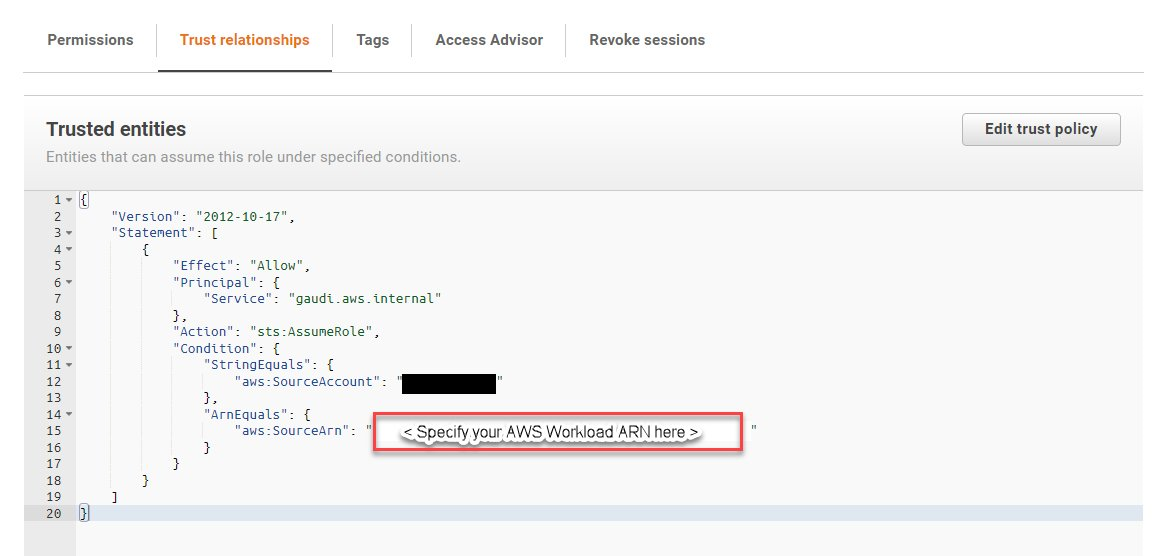
  3. To collect Trusted Advisor checks from accounts other than the account where the workload you are reviewing exists, you must perform two steps. You need to ensure the account IDs are listed in the workload properties for the workload you are reviewing. You must then create an IAM role in the account from which Trusted Advisor checks will be collected with the following permission and trust relationship (Figures 7 and 8). For more information on how to setup this permission, refer to the feature documentation.
    Permissions needed by AWS Well-Architected Tool to interrogate AWS Trusted Advisor

    Figure 7. Permissions needed by AWS Well-Architected Tool to interrogate AWS Trusted Advisor

    The trust relationship allowing AWS Well-Architected Tool to assume policy on behalf of the workload

    Figure 8. The trust relationship allowing AWS Well-Architected Tool to assume policy on behalf of the workload

Using integration with AWS Trusted Advisor for insights during reviews

Once the feature is enabled, additional insights will be noticeable about the resources in your workload using Trusted Advisor checks. Let’s explore an example question. In this case, we will use Question 9 from the Reliability Pillar, as there are Trusted Advisor checks related to the best practices in it: How do you back up data?

  1. AWS Well-Architected Reliability Question 9 includes best practices that are related to how workload backup is performed to support the ability for the workload to recover from failure. Current findings using Trusted Advisor checks indicates the workload may not be configured based on the “Perform data backup automatically” best practice in the Reliability Pillar (Figure 9).

    "Perform data backup automatically" best practices

    Figure 9. “Perform data backup automatically” best practices

  2. To access Trusted Advisor checks as insights, you can select a question in the Well-Architected Tool (Figure 10). If there are related Trusted Advisor checks available for a question, there will be a “View checks” button like the screenshot below. You can also select the “Trusted Advisor checks” tab.

    Trusted Advisor checks that map to best practices

    Figure 10. AWS Trusted Advisor checks that map to best practices

  3. Trusted Advisor checks are available, which provide insights related to the best practice in the question. You will also notice the state of resources recommendations and the count of resources. Trusted Advisor checks that relate to the best practice “Perform data backup automatically” are displayed. One of the Trusted Advisor checks identified with a x in a circle (denoting “Action recommended”) status is on the Amazon Elastic Block Storage (Amazon EBS) snapshots availability to recover your EBS volume from in the event of disaster (Figure 11).

    AWS Trusted Advisor check for Amazon EBS snapshots with "Action recommended"

    Figure 11. AWS Trusted Advisor check for Amazon EBS snapshots with “Action recommended”

  4. Exploring the Trusted Advisor Console, you can identify the EBS volume ID that has been detected with no snapshot in this us-west-2 region (Figure 12).

    An EBS volume that does not have snapshots

    Figure 12. An EBS volume that does not have snapshots

  5. With the insights from Trusted Advisor, we can quickly determine that the “Perform data backup automatically” best practice is not in place, as we do not have Amazon EBS snapshots enabled. Through the “helpful resources” section, instructions can be found to help automate the snapshot creation of Amazon EBS volume (Figure 13). One method to achieve this is to use AWS Backup.

    Resources with details about best practices, including links to learn more

    Figure 13. Resources with details about best practices, including links to learn more

  6. Using AWS Backup you can define a backup plan to automate snapshots creation of the EBS volume. Using this plan, you adjust the frequency of the backup to help achieve your recovery time objective and recovery point objective (Figure 14). For more information on how to configure EBS volume backup plan, refer to the Developer Guide on creating a backup plan.

    Setup automatic Amazon EBS volume snapshots

    Figure 14. Setup automatic Amazon EBS volume snapshots

  7. Once this improvement is implemented and the related EBS volume snapshot is taken, Trusted Advisor will reflect the changes to the resource (Figure 15).

    Amazon EBS volume with a snapshot

    Figure 15. Amazon EBS volume with a snapshot

  8. The next time we perform a Well-Architected Framework Review on this workload, the related AWS Trusted Advisor Check will show no action required with a check-mark status (Figure 16).
    AWS Trusted Advisor checks that represent improvements that have been implemented

    Figure 16. AWS Trusted Advisor checks that represent improvements that have been implemented

    Optional: For access to the list of Trusted Advisor checks in .csv format, you can click on the “Download check details” button on each question to download the resources that were checked in relation to the specified best practices (Figure 17).

    "Download check details" button

    Figure 17. “Download check details” button

  9. Once implemented, this improvement ensures a means to recover the EBS volume data in the event of disaster. This makes the resources in the workload better aligned to the AWS Reliability Pillar Design principle of “Automatically recover from failure”. To reflect this alignment in the Well-Architected Tool, you can tick on the best practice check items under the related questions (Figure 18).

    A milestone with updated best practices based on improvements that have been implemented

    Figure 18. A milestone with updated best practices based on improvements that have been implemented

  10. Finally, you can create a milestone to capture a point in time state of your workload WAFR. As you continuously optimize with more WAFRs and improvements, the number of high- and medium-risk items identified within each review will decrease. You will notice the continuous optimization of your workload over time, as in Figure 19.

    The history of improvements being made over time

    Figure 19. The history of improvements being made over time

Conclusion

Using the AWS Well-Architected integration with AWS Trusted Advisor, customers have a mechanism to accelerate the “learn, measure, and improve” Well-Architected virtuous cycle, creating an optimization flywheel. We have demonstrated the value of creating acceleration through the insights from Trusted Advisor checks. You now know how to enable the integration with Trusted Advisor and have seen an example of how the insights can accelerate your review cycle. You will notice the improvements you make over time will reflect in the Trusted Advisor checks as you review the milestones for your workloads. Enable this feature on your next Well-Architected Framework Review (WAFR) to measure the impact that data-driven insights from Trusted Advisor can have on reducing the time-to-value for your reviews. For more information consider these additional resources. You can contact your account team for support in running WAFRs or check out the AWS Well-Architected Partner Program to find a partner that can help you run a review. Additionally, running a WAFR with a partner assisting you in remediating risks may also provide funding credits to offset the costs required to make the improvements.

“Perform data backup automatically” is part of the Reliability Pillar of the AWS Well-Architected Framework. AWS Well-Architected is a set of guiding design principles developed by AWS to help organizations build secure, high-performing, resilient, and efficient infrastructure for a variety of applications and workloads. Use the AWS Well-Architected Tool to review your workloads periodically to address important design considerations and ensure that they follow the best practices and guidance of the AWS Well-Architected Framework. For follow up questions or comments, join our growing community on AWS re:Post.


Defeating Phishing-Resistant Multifactor Authentication

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/11/defeating-phishing-resistant-multifactor-authentication.html

CISA is now pushing phishing-resistant multifactor authentication.

Roger Grimes has an excellent post reminding everyone that “phishing-resistant” is not “phishing proof,” and that everyone needs to stop pretending otherwise. His list of different attacks is particularly useful.

Enriching operational events with AWS Serverless

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/enriching-operational-events-with-aws-serverless/

This post was written by Ben Moses, Senior Solutions Architect, Enterprise.

AWS Serverless is a fit for many IT automation and operations use cases, especially for reacting to events. Infrastructure events are a useful way to understand the health of your infrastructure that supports your applications and customers and this blog examines using serverless to help enrich these operational events.

The scenario used in this post shows how an infrastructure event can be intercepted in real-time, enriched with additional information from your AWS environment and workloads, and be sent to a downstream consumer with the added valuable information.

This example focuses on Amazon EC2 state change events. The concept applies to any type of event, for example those emitted by other AWS services to Amazon CloudWatch Events. These events could also include events produced by AWS Config, and some of AWS CloudTrail’s events, including CloudTrail Insights.

The purpose is to add more valuable information and context to events in real-time. Operators and downstream consumers can then identify emerging patterns in near real-time.

How does this happen today?

It is common for existing solutions to store infrastructure events in whatever format the source system generates, or in a standardized open or proprietary format. Operations staff and systems then analyze these logs to understand patterns and to support root cause analysis. This data must often be enriched by other sources to give it context and meaning. This is done either in a scheduled batch operation by using CSV data from other systems, or by integrating with other enterprise tooling.

The state of your cloud infrastructure changes frequently due to the elasticity and disposability of resources. This can cause an issue with your data quality when using the schedule batch method. When you come to enrich an infrastructure event, the state may have changed by the time your scheduled batch runs. This leads to gaps or inaccuracies in data, which makes it harder for operators to spot trends and anomalies.

A serverless approach

This example uses serverless services and concepts from event driven architecture (EDA). With this architecture, you only pay when events happen and are enriched. There’s no need for any third-party tooling, and your events are enriched in near real-time.

The EC2 “State Change Event” is enriched by obtaining the instance’s name tag, if it has one. The end-to-end journey look like this:

Overview

  1. An EC2 instance’s state changes (i.e., shutdown, restart).
  2. An Amazon EventBridge rule that matches the event pattern triggers a target action to run an AWS Step Functions state machine.
  3. The state machine transforms inputs, makes a native AWS API SDK call to the EC2 service to find a name tag, and emits a newly enriched event back to EventBridge.
  4. An EventBridge rule matching the enriched event triggers an action to send an email via Amazon SNS to simulate a downstream consumer.

EventBridge is a serverless event bus that can be used with event driven architectures on AWS. An EventBridge rule is defined with a pattern, and if an event matches that pattern, then the rule’s target action is triggered. In this example, the rule is:

{
  "detail-type": ["EC2 Instance State-change Notification"],
  "source": ["aws.ec2"]
}

An EC2 state change event looks like this:

{
  "version": "0",
  "id": "672123fe-53aa-3b22-3b37-1fae26df2aff",
  "detail-type": "EC2 Instance State-change Notification",
  "source": "aws.ec2",
  "account": "1234567890",
  "time": "2022-08-17T18:25:01Z",
  "region": "eu-west-1",
  "resources": [
    "arn:aws:ec2:eu-west-1:1234567890:instance/i-1234567890"
  ],
  "detail": {
    "instance-id": "i-0123456789",
    "state": "running"
  }
}

See the detail-type and source fields in the event. These match the rule and this entire event payload is passed on to the next component of the architecture: the Step Functions state machine.

Step Functions uses JSONPath to select, transform, and move data through the states within a state machine. This flexibility means that, in this example, no compute resources such as AWS Lambda are required. This can mean less custom code, lower cost, and less complexity.

Step Functions Workflow Studio lets you design workflows visually. These are the key actions that take place when the state machine runs using the EC2 state change event:

Step Functions state machine

1. Remove problem characters from input

Pass states allow us to transform inputs and outputs. In this architecture, a Pass state is used to remove any problem characters from the incoming event that are known to cause issues in future steps, such as API calls to services.

In this example, the parameters for the API call used in Step 2 requires the EC2 instance ID. This information is in the detail of the original event, but the API action can’t use anything with a hyphen in it.

To solve this, use a JSONPath Parameter to effectively rewrite this information without the hyphen. This creates a new field named instanceid, which is assigned the value from the original event’s detail.

{
  "instanceid.$": "$.detail.instance-id"
}

2. Get instance name from Tag

The “EC2: DescribeInstances” task in Step Functions is an example of a native SDK integration with an AWS service. This action expects a single parameter to the API, an array of EC2 instance IDs.

{
  "InstanceIds.$": "States.Array($.detail.refined.instanceid)"
}

The States.Array() intrinsic function is used to wrap the instance ID from the re-written field created in step 1. This single-member array is then passed to the EC2 Describe Instances API.

When a response is received from the EC2 Describe Instances API call, it is passed to a Result Selector. The purpose of this is to extract the value of a “Name” tag, if one was returned from the EC2 Describe Instances API.

Step Functions supports the use of JSONPath filter expressions.

{
  "instancename.$": "$..Reservations[0].Instances[0].Tags[?(@.Key==Name)].Value",
  "instanceid.$": "$.Reservations[0].Instances[0].InstanceId"
}

To understand the advanced JSONPath filter expression used in this example, read this blog post.

If an error occurs with the API call, or the filter expression is unable to find a “Name” tag on the EC2 instance, then Step Functions allows you to handle these errors within the workflow.

3. Convert instance name to a string

The output from the previous state returns an array, but an EC2 instance can only have one unique “Name” tag. A pass state is used again, with a parameter as seen in Step 1. This parameter expression takes the first element from the array and stores it in a new field named instancename.

{
  "instancename.$": "$.detail.refined.instancename[0]",
  "instanceid.$": "$.detail.refined.instanceid"
}

As with previous steps, the instanceid is re-written as part of the output, and both of these values are appended to the state’s output.

4. Get default name from Parameter Store

If the filter expression in the result selector in step 2 fails for any reason, then Step Functions error handling moves here.

Failures can happen for a variety of reasons, and with Step Functions, you can branch out error handling for each different error type. In this example, all errors are dealt with the same regardless of the cause being a missing “Name” tag, or a permissions issue. In this architecture, a default placeholder value is used in place of the name of the instance. In your context, a different approach may be more suitable.

The default placeholder name is stored as a static value in AWS Systems Manager Parameter Store. The native Systems Manager: GetParameter action within Step Functions can retrieve this value directly. An advantage of this approach is that the parameter can be updated externally without having to make any changes to the Step Functions state machine itself.

5. Add ID back to refined

A pass state is used to format the response from the Parameter Store API and parameter expression then appends the default instance name on to the output.

Whether the workflow execution followed the intended execution path, or encountered an error, there is now an enriched event payload with an instance name.

6. Emit enriched event

The EventBridge: PutEvents native SDK action within Step Functions is used to construct and emit the enriched event.

{
  "Entries": [
    {
      "Detail": {
        "Message.$": "$"
      },
      "DetailType": "EnrichedEC2Event",
      "EventBusName": "serverless-event-enrichment-ApplicationEventBus",
      "Source": "custom.enriched.ec2"
    }
  ]
}

The DetailType and Source of the enriched event are custom values, specified in the last step of the state machine. As you consider schemas for your events within your organization, note that the AWS prefix is reserved for AWS service events.

The enriched event payload looks like this:

{
  "version": "0",
  "id": "a80e378b-e9a7-8007-1f18-b947e6d72c4b",
  "detail-type": "EnrichedEC2Event",
  "source": "custom.enriched.ec2",
  "account": "123456789",
  "time": "2022-08-17T18:25:03Z",
  "region": "eu-west-1",
  "resources": [
    "arn:aws:states:eu-west-1:123456789:stateMachine:EventEnrichmentStateMachine-2T5jFlCPOha1",
    "arn:aws:states:eu-west-1:123456789:execution:EventEnrichmentStateMachine-2T5jFlCPOha1:672123fe-53aa-3b22-3b37-1fae26df2aff_90821b68-ba92-2374-5015-8804c8da5769"
  ],
  "detail": {
    "Message": {
      "version": "0",
      "id": "672123fe-53aa-3b22-3b37-1fae26df2aff",
      "detail-type": "EC2 Instance State-change Notification",
      "source": "aws.ec2",
      "account": "123456789",
      "time": "2022-08-17T18:25:01Z",
      "region": "eu-west-1",
      "resources": [
        "arn:aws:ec2:eu-west-1:123456789:instance/i-123456789"
      ],
      "detail": {
        "instance-id": "i-123456789",
        "state": "running",
        "refined": {
          "instancename": "ec2-enrichment-demo-instance",
          "instanceid": "i-123456789"
        }
      }
    }
  }
}

Consuming enriched events

When enriching event data in real-time, the events are only valuable if they’re consumed. To use these enriched events, a consuming service must create and own a new EventBridge rule on the custom application bus. In this architecture, an appropriate rule pattern is:

{
  "detail-type": ["EnrichedEC2Event"],
  "source": ["custom.enriched.ec2"]
}

The target of the rule depends on the use case. For operational events, then service management applications or log aggregation services may make the most sense. In this example, the rule has an SNS topic as the target. When SNS receives a message, it is sent to operator via email. With EventBridge, future consumers can add their own rules to match the enriched events, and add their specific target actions to suit their use case.

Conclusion

This post shows how you can create rules in EventBridge to react to operational events from AWS services. These events are routed to Step Functions, which runs a workflow consisting of steps to enrich the event, handle errors, and emit the enriched event. The example shows how to consume the enriched events, resulting in an operator receiving an email.

This example is available on GitHub as an AWS Serverless Application Model (AWS SAM) template. It contains instructions to deploy, test, and then remove all of the resources when you’ve finished.

For more serverless learning resources, visit Serverless Land.

Разследване на Валя Ахчиева: Горско правосъдие

Post Syndicated from Екип на Биволъ original https://bivol.bg/%D0%B3%D0%BE%D1%80%D1%81%D0%BA%D0%BE-%D0%BF%D1%80%D0%B0%D0%B2%D0%BE%D1%81%D1%8A%D0%B4%D0%B8%D0%B5.html

сряда 9 ноември 2022


И какво?  Какво като ходим по горите и показваме незаконна сеч или законна сеч в комплект с незаконни горски пътища? Какво като показваме на екрана  стотици кадри с отсечени стогодишни…

Ани Ерно, автофикцията и дългата сянка на #MeToo

Post Syndicated from Меглена Боденска original https://toest.bg/annie-ernaux-nobel-prize-me-too/

„Глас от небето“

На 6 октомври 2022 г. по обяд литературният свят е затаил дъх в очакване да бъде обявено името на нобелиста за литература. Телефонът на 82-годишната французойка Ани Ерно упорито звъни. Тя не отговаря, оставя го за по-късно, когато приключи работа. В този момент Арно е заета с присъщото на писателите занимание: писане.

В 13:00 часа шведско време Матс Малм, постоянният секретар на Шведската академия, съобщава, че високото отличие се присъжда на Ани Ерно за „куража и клиничната прецизност, с които разкрива корените, отчуждението и колективните ограничения на личната памет“. Пред телевизионния екран в апартамента си в Стокхолм Мария Бьоркман, шведската преводачка на писателката, се разплаква и прегръща кучето си – била е убедена, че няма да наградят Ерно, защото… е спрягана за фаворит!

Матс Малм добавя, че не са успели да се свържат с Ани Ерно, но се надяват тя скоро да научи новината. Думи стряскащи за онези, които си спомнят неловкото положение с Боб Дилън през 2016 г. – Шведската академия не получи никаква вест от него цели две седмици. През изминалите шест години августейшият блясък на институцията е помръкнал (повече за това – по-нататък) и тя няма кредит за повече „неловкости“.

Новината достига Ерно един час по-късно. Тя е сама, в кухнята на каменната си къща в парижкото предградие Сержи, където живее от 40 години. Слуша радио, за да разбере кой е нобелистът за литература. Когато чува своето име, чувството било „сякаш сте в пустинята и изведнъж някой ви заговаря от небесата“, споделя тя по-късно в телефонно интервю за Нобеловата фондация.

Съвсем скоро Ерно – сърдечна, одухотворена, по момичешки витална – се свързва с Шведската академия. Отговаря, че за нея отличието е „голяма отговорност и едновременно с това – чест“. Отговорност да продължи борбата срещу несправедливостите, извършвани не само спрямо жените, а и спрямо „доминираните“, ако използваме термина на френския социолог Пиер Бурдийо.

Нобеловото жури може да си отдъхне.

Критериите за литературния „Нобел“

Нека припомним, че според завещанието на дарителя Алфред Нобел наградите, носещи неговото име, се връчват „на онези, които през изминалата година са допринесли най-много за благото на човечеството“. Нобел е казвал, че иска да помогне на хора мечтатели, които трудно си пробиват път. Разпоредил е също така в областта на литературата да се награждава онзи, който „е създал най-забележителната творба с идеалистична насоченост“.

Разковничето тук е в тълкуванието на израза „идеалистична насоченост“. То се е менило през десетилетията, най-вече спрямо идейно-естетическите възгледи на водещите фигури във вътрешния Нобелов комитет на Шведската академия. Това е група от петима членове, които пресяват кандидатите до кратък списък от около пет имена. След това решението се обсъжда и гласува от всички 18 членове на Академията. Хуманизмът и идеализмът, които са предпоставка за награждаване, често остават неразбрани. Може да изглежда, че Шведската академия пренебрегва всепризнати майстори на изящната словесност, а отдава предпочитанията си на творци с изявена политическа позиция.

Предвид благородните критерии, заложени от Алфред Нобел, Ани Ерно е повече от добър избор. Освен това тя се вписва в силната традиция на работническата литература в Швеция, както и в коренно променения обществен климат след движението #MeToo.

Деликатното положение на Нобеловото жури

Изборът на Ерно обаче ще остане недоразбран, ако не се вземе предвид особеното положение на Шведската академия към момента.

През последните години институцията имаше повод добре да си припомни заветите на Нобел. Грандиозният скандал, подпален от движението #MeToo през 2017 г., разкри редица нередности. Скандалът избухна, когато 18 жени свидетелстваха, че са били жертви на сексуално насилие и тормоз от страна на съпруга на тогавашната членка на Шведската академия Катарина Фростенсон. По-късно две от жените повдигнаха обвинения за изнасилване срещу Жан-Клод Арно и той беше осъден на две години затвор. Паралелно с този скандал стана ясно и това, че Арно през годините е разпространил предварително имената на поне седем литературни лауреати. (Темата е изчерпателно представена в документалния роман „Клубът“ на Матилда Вос Густавсон, София: Гутенберг, 2022 г.)

След масовите оставки през 2018 г. се наложи крал Карл ХVI да промени Устава на Шведската академия, с което на членовете на институцията беше дадено право да напуснат по собствено желание (дотогава длъжността е била пожизнена, оставки не се приемали, а местата оставали незаети до смъртта на съответното лице) и беше въведено правилото членовете, които са били неактивни повече от 2 години, автоматично да бъдат отстранени.

По-късно към вътрешния Нобелов комитет на Академията бяха присъединени петима външни членове за период от 2 години, но някои от тях напуснаха с гръм и трясък след избора на Петер Хандке през 2019 г. Тогава бе направена още по-сериозна промяна: 3-годишни мандати за членовете на вътрешния комитет. През 2020 г. бяха поканени и 10 външни експерти (без право на глас) от различни езикови области. В бъдеще не са изключени и други реформи.

До 2021 г. грозната сянка на скандалите около литературните Нобелови награди не се беше разсеяла. След представянето на лауреата Абдулразак Гурна шведските медии обсипаха председателя на вътрешния Нобелов комитет Андерш Улсон с въпроси дали престижът на наградата не е уронен.

Писателският път на Ерно

Ани Ерно е родена на 1 септември 1940 г. в Лилбон, Нормандия, и израства в Ивто, градче в същата област. Там родителите на Ерно държат кафене и бакалия. За тях това е стъпало нагоре в обществото, защото произхождат от семейства на безимотни селяни. Майката на Ерно е решена да даде на дъщеря си онова, което самата тя не е имала: добро образование. Малката Ани е изпратена в частен католически пансион. Получава и висше образование, става учителка по литература. Вече се числи към буржоазията, а не към работническата класа и това отваря пропаст между нея и света, от който произхожда. Оттук нататък ще се чувства своя сред чужди и чужда сред свои. „Отчуждението“, назовано в обосновката на Шведската академия, е високата цена на социалния възход.

Ани Ерно осъзнава, че иска да стане писателка, на 22-годишна възраст, след като написва роман, който е отхвърлен. Мисълта да продължи да пише не ѝ дава мира, но се намесва животът – тя забременява, прави незаконен аборт, по-късно се омъжва и ражда двамата си сина. Най-накрая, когато е на 32, намира време да пише. „Сякаш не можех повече да живея, без да пиша. И все още е така“, споделя Ерно в интервю за литературното предаване Babel („Вавилон“) на Шведската телевизия.

Нейните първи три публикувани творби са художествени с автобиографични мотиви. Ерно обаче намира своя уникален разказвачески глас през 1983 г. с четвъртото си произведение – La Place („Мястото“). Повестта е литературният пробив на Ерно, с него печели наградата „Ренодо“ за 1984 г. и впоследствие е преведена на няколко езика.

В „Мястото“ (на френски думата има социална конотация, подразбира се като „мястото в обществото“) Ерно търси истината и нищо освен истината за покойния си баща. Слага на операционната маса, под безжалостната светлина на хирургическите лампи, спомените си за него и ги описва „с клинична прецизност“. Стилът на Ерно се отличава с безкомпромисна откровеност, простота и отсъствие на смекчаваща ирония и сантимент. Ето как го определя самата тя в „Мястото“ (прев. от фр. Светлана Даскалова, към сборника „С най-хубав спомен“, съст. Николай Стоянов, София: Народна култура, 1986):

Никаква поезия на спомена, нито ликуваща насмешливост. Равният стил ми се налага естествено, същият, който използвах някога в писмата до родителите си, за да им съобщя важни новини.

Откровеността на Ерно е повече от недискретност, тя граничи с предателство към средата, от която произлиза:

Говорехме си винаги сопнато. Учтивият тон беше запазен за чуждите хора. Навикът бе тъй силен, че макар да говореше правилно в присъствието на други, за да ми забрани да се катеря по купчина камъни, баща ми се връщаше към грубия тон, нормандския акцент, и заличаваше доброто впечатление. Не се беше научил да ми се кара изискано, пък и аз не бих повярвала в заплаха от плесница, изречена граматически правилно.

„Да пиша не означава за мен да протягам ръце към небето, а да дълбая, да се заровя в нещо“, обобщава Ерно. Темите ѝ са изключително автобиографични, от кориците на книгите ѝ често ни гледат нейни черно-бели фотографии. Авторката описва лица, събития и фрагменти като безстрастен страничен наблюдател. Но тази хладност е подвеждаща. „Чувствата нямат място в творбите ми – те не са описание на чувства“, казва Ерно, но с клиничната си дистанцираност текстовете ѝ по удивителен начин събуждат емоциите на читателя.

През дългия си творчески път Ани Ерно е написала над 20 романа. Тя не крие, че е повлияна от Марсел Пруст и неговия опус „По следите на изгубеното време“, но също и от Пиер Бурдийо – социолога, съставил диаграми на различните вкусове и привички на работническата и на средната класа.

Сред по-значимите произведения на Ерно е Une Femme („Eдна жена“) от 1987 г., роман за нейната майка, силна и волева жена, която към края на живота си страда от деменция. Обрисувайки детайлно материалната страна на реалността, Ерно изважда наяве красотата и в най-мъчителните сцени. За по-късната си книга на същата тема Je ne suis pas sortie de ma nuit („Не съм излязла от нощта си“) Ерно казва в интервю пред Деница Банчева за в. „Литературен форум“ през 1997 г.:

… когато описвам общуването между майка ми и една друга възрастна жена, която страда от болестта на Алцхаймер и лежи в същата стая, красотата се появява – макар че и двете са изгубили паметта си и не разбират какво си говорят, те се държат за ръце и преливат една в друга нещо топло, нежно… Струва ми се, че тази сцена е красива като картина на Джото, че изразява абсолютната красота на човешкото.

През 1997 г. е публикуван романът La honte („Срамът“), своего рода продължение на „Мястото“. Още от първото изречение на творбата става ясна темата му: 12-годишната Ани Ерно вижда как баща ѝ се опитва да убие с брадва майка ѝ в мазето. Срамът и чувството, че произлиза от простолюдна среда, породени от страшната сцена, никога не я напускат. Тя казва, че може би това травматично преживяване я е направило писателка.

Ерно не търси темите си, те я намират сами, а понякога узряват у нея с години. Но има общ знаменател между тях: „Пиша книги, за които после не мога да говоря, които правят чуждите погледи непоносими за мен.“

Като шедьовър в творчеството на Ерно Шведската академия откроява романа L’événement („Събитието“) от 2000 г. Той разказва за нелегалния ѝ аборт през 60-те години на ХХ век. Процедурата едва не я убива, а горчивината е още по-голяма заради презрението, което среща у околните. Романът е екранизиран през 2021 г. от Одре Диуан, писателка и режисьорка от френско-ливански произход. По-късно филмът печели „Златен лъв“ на 78-мия Международен филмов фестивал във Венеция.

Най-мащабният проект на Ерно, нейният magnum opus, e романът Les années („Годините“) от 2008 г., който попада в краткия списък на Международната награда „Букър“ през 2019 г. „Годините“ описват десетилетията след Втората световна война през призмата на живота на една жена. Разказът обаче е от първо лице множествено число и романът е наричан „първата колективна автобиография“. Очаква се „Годините“ да бъде публикуван на български до края на 2022 г. от издателство „Лист“ в превод на Валентина Бояджиева.

През 2016 г., в навечерието на движението #MeToo, Eрно публикува Mémoire de fille („Мемоарите на едно момиче“) – разказ за друга травма от младостта ѝ: как губи девствеността си в акт на границата между съгласието и принудата, докато е на летен лагер в Нормандия.

Сред творбите, върху които акцентира Шведската академия в представянето на Ерно, се откроява обаче липсата на едно ключово заглавие – Passion simple („Обикновена страст“) от 1992 г. Тъничката книжка разбунва страстите у френските читатели. Шведският превод излиза само година по-късно и придобива култов статус. Романът е публикуван и на български по същото време, но остава без отзвук у нас.

Краткият роман разказва за сексуалната връзка на разведената Ерно с по-млад женен мъж. Той е изпратен от източноевропейска държава на работа в Париж, харесва костюмите на „Ив Сен Лоран“, вратовръзките на „Черути“ и големите коли – и пие много, „нещо обичайно в източноевропейските страни“. Страстта пламва и угасва със заминаването на фаталния мъж през 1989–1990 г., времето на падането на Берлинската стена и ламбадата. Но епохата е само фонов шум, единствената реалност е вътрешната („Обикновена страст“, прев. от фр. Нона Стефанова, София: Прозорец, 1994):

От септември миналата година вече не правех нищо, само чаках, чаках един мъж да ми се обади и да дойде. Ходех в супермаркета, на кино, носех дрехи за гладене, четях, поправях писмени работи, вършех всичко точно както преди, но ако нямах старите навици, изпълнението на тези действия щеше да ми бъде невъзможно без някакво невероятно усилие. Особено когато говорех, имах чувството, че живея по инерция. Думите, изреченията, дори смехът се оформяха в устата ми без истинското участие на волята. Впрочем за тогавашните ми постъпки, за филмите, които съм гледала, за хората, с които съм се срещала, ми е останал само смътен спомен.

Френските читатели са развълнувани от моралния аспект на книгата, а някои я възприемат като унижение на жената, разказва Ерно пред Шведското радио през 1998 г. Любителките на любовни романи са разочаровани от отсъствието на поезия, романтика и сексуални подробности. Други смятат, че книгата описва нещата от живота такива, каквито са. Трети критикуват Ерно за пълната липса на свян, четвърти – че се държи недостойно за интелектуалка: слуша естрадни песни на Силви Вартан вместо класическа музика, купува си червило. Но читатели мъже се припознават в написаното от нея и са изненадани, че авторката е жена.

Списание „Мари Клер“ прави анкета дали книгата е феминистка, или не. Отговорът е „да“, защото мъжът е обект. „Обикновена страст“ е екранизирана през 2020 г. от френската режисьорка Даниел Арбид. Главните роли изпълняват Летисия Дош и руският балетист Сергей Полунин. Тези, които очакват сексуални подробности, този път няма да останат разочаровани.

Влиянието на Ерно върху по-младото поколение писатели

През последните десетилетия безстрастният автобиографичен стил на Ерно е намерил последователи. Шведската литературна критичка Улрика Милес нарича Ани Ерно „прамайка на автофиктивната вълна“:

Eрно има неколцина наследници в течението на автобиографичното писане, заляло през последното десетилетие особено Скандинавия, с автори като Рейчъл Куск, Вигдис Йорт, Карл Уве Кнаусгор. Това течение има свои представители и сред младите френски писатели, например Едуар Луи и Нина Бурауи, които имат набито око за ефекта на нисшия социален произход върху живота на индивида.

Реакциите в Швеция

Удостояването на Ерно с Нобелова награда бе прието радушно в Швеция, без да е голяма изненада. Във връзка с възродения интерес към книгите ѝ – в последните години бяха преиздадени ключовите творби на писателката, а през 2023 г. предстои да излезе шведският превод на най-новия ѝ роман Le jeune homme („Младият мъж“) – нейното име често се появява в медиите и беше на челните места в списъците на фаворитите за „Нобел“ на компаниите за залагания.

Автобиографичният есеистичен стил на Ерно улавя духа на времето, но всъщност доколко актуалните тенденции вълнуват Шведската академия, пита се литературната критичка Анина Рабе. Без съмнение Ани Ерно е достойна за „Нобел“, но все пак е интересно да се отчетат механизмите, издигнали я на литературния Олимп тъкмо сега, коментира критичката.

Други говорят без заобикалки. С избора на Ерно Шведската академия цели да остави годините на скандали зад себе си и да затвори главата, която бе принудена да отвори от движението #MeToo, смята Ханес Фосбу от културната редакция на Шведската телевизия.

Като „очакван, класически и популярен“ и „опит за прелъстяване на читателската публика“ определя избора Бьорн Виман от авторитетния шведски ежедневник „Дагенс Нюхетер“. За Виман изборът е дело на „новата“ Академия – половината от настоящите членове са избрани след 2018 г., като една трета са жени, най-голямото процентно съотношение в над 230-годишната история на институцията.

Улрика Милес смята, че от 2007 г. насам, когато „Нобел“ за литература получи Дорис Лесинг, „сенките на женското (нелегални аборти, сексуални посегателства, роли на любовница, разводи) са се нормализирали, женското се е приравнило с общочовешкото“.

Разбира се, има и не толкова възторжени гласове, които критикуват, че за пореден път е отличен писател, езикът на чиито творби е индоевропейски. А други намират разказа за борбата на една хетеросексуална жена да строши оковите на патриархата за… изтъркан и скучен.

Тази година Шведската академия насочи прожектора на славата към стойностна авторка, позната на ценителите на литературата в държавите с по-голям културен пазар, но почти анонимна у нас. Да, Ерно присъства с два превода на български и в задълбоченото интервю на Деница Банчева, но те са останали някак незабелязани. Да се надяваме, че Нобеловата награда ще ни помогне да я преоткрием.

Заглавна снимка: Стопкадър от интервю с Ани Ерно в предаването Pagina Dos по RTVE от май 2022 г. 

Източник
A New AWS Region Opens in Switzerland

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/a-new-aws-region-opens-in-switzerland/

I am pleased to announce today the opening of our 28th AWS Region: Europe (Zurich), also known by its API name: eu-central-2.

An AWS Region allows you to deploy your most demanding workloads and replicate your applications and data across distinct groups of data centers called Availability Zones. This new Region has three fully redundant Availability Zones located in the vicinity of Zurich. It offers your customers low-latency access to your applications while meeting your data residency requirements.

Zurich

Regions and Availability Zones
AWS has the concept of a Region. Each Region is fully isolated from all other Regions. Within each Region, we have built Availability Zones. These Availability Zones are fully isolated partitions of our infrastructure that contain a cluster of data centers. Availability Zones are typically separated by multiple kilometers to mitigate the impact of disasters that could affect data centers. The distance between Availability Zones varies between Regions. The distance is large enough to avoid having data centers impacted by the same event at the same time but close enough to allow workloads with synchronous data replication. Availability Zones are linked by redundant, high-bandwidth, and low-latency network connections. Regions are linked by our custom-built, global, low-latency, private network with exabits per second of capacity in Europe.

Unlike other cloud providers, who often define a region as a single data center, the multiple Availability Zone design of every AWS Region offers advantages such as security, availability, performance, and scalability.

Instances and Services
The workloads deployed to this new Europe (Zurich) three-AZ Region can use C5, C5d, I3, I3en, M5, M5d, M6gd, R5, R5d, and T3 instances, and can use a long list of AWS services including Amazon API Gateway, AWS AppConfig, AWS Application Auto Scaling, Amazon Aurora, Amazon EC2 Auto Scaling, AWS Config, AWS Certificate Manager, AWS CloudFormation, AWS CloudTrail, Amazon CloudWatch, Amazon CloudWatch Events, Amazon CloudWatch Logs, AWS CodeDeploy, AWS Database Migration Service (AWS DMS), AWS Direct Connect, Amazon DynamoDB, Amazon Elastic Block Store (Amazon EBS),Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Registry (Amazon ECR), Amazon Elastic Container Service (Amazon ECS), AWS Fargate,  Amazon ElastiCache, Amazon EMR, Amazon OpenSearch Service, Elastic Load Balancing, Elastic Load Balancing – Network (NLB), Amazon EventBridge, Amazon Simple Storage Service Glacier, AWS Identity and Access Management (IAM), Amazon Kinesis Data Streams, AWS Key Management Service (AWS KMS), AWS Lambda, AWS Marketplace, AWS Health Dashboard, Amazon Relational Database Service (Amazon RDS), Aurora PostgreSQL, Amazon Redshift, Amazon Route 53, Amazon Virtual Private Cloud (Amazon VPC), AWS Secrets Manager, Amazon Simple Storage Service (Amazon S3), Amazon Simple Notification Service (Amazon SNS), Amazon Simple Queue Service (Amazon SQS), AWS Step Functions, AWS Support API, Amazon Simple Workflow Service (Amazon SWF), AWS Systems Manager, AWS Trusted Advisor, VM Import/Export, AWS VPN, and AWS X-Ray.

Continuous Investments in Switzerland
AWS has a long history of presence in Switzerland. We have worked with Swiss customers and partners since the launch of AWS 16 years ago. The first Swiss office was opened in Zurich in April 2016 to host the growing local team of technical and business professionals dedicated to supporting Swiss customers. In 2017, the AWS network was expanded into Switzerland with the launch of an Amazon CloudFront edge location and an AWS Direct Connect location. To support this growth, a second AWS office was opened in Geneva.

AWS plans to invest up to 5.9 billion Swiss francs (approximately $5.9 billion) in the Europe (Zurich) Region from 2022–2036 as we build, maintain, operate, and develop data centers to support the projected growth in demand for AWS technologies by our customers.

According to an AWS Economic Impact Study (EIS), this investment will contribute 16.3 billion Swiss francs (approximately $16.3 billion) to the GDP of Switzerland during the same period. This includes the value added by AWS services to the IT sector in Switzerland, as well as the direct, indirect, and induced effects of AWS purchases from the Swiss data center supply chain. The study estimates that this investment will support an average of 2,500 full-time jobs annually at external businesses in the Swiss data supply chain from 2022–2036.

Servicing our Swiss Customers
More than 10,000 Swiss customers use AWS services today. Organizations such as Fisch Asset Management, Helvetia, Eidgenössische Technische Hochschule Zürich (ETH Zürich), Richemont, Swiss Broadcasting Corporation (RSI), Swiss Post, Swisscom, and Swisstopo, just to name a few, use AWS. Private and public sector organizations in Switzerland use AWS to accelerate their time to market, reduce costs associated with IT operations, and scale their businesses globally.

Global luxury group Richemont, owners of prestigious brands like Cartier, Montblanc, IWC Schaffhausen, and Van Cleef & Arpels, moved its entire enterprise IT infrastructure, including 120 SAP instances, to AWS. AWS, with its depth and breadth of services, enables Richemont to provide their customers with new digital experiences faster, including personalized storefronts and styling services, video chat consultations featuring fashion shows customized to the shoppers’ tastes, and tailored offers for early access to new items before they hit stores.

Swisscom, Switzerland’s leading telecoms company and one of its leading IT companies, is using AWS’s proven and broad infrastructure and cloud capabilities to power its 5G network, increase operational efficiency, and fuel innovation. Swisscom is pursuing a cloud-first strategy and will use AWS to increase IT agility, drive operational efficiencies, and accelerate time to market for new information and communications technology (ICT) features and services.

With AWS infrastructure, Swiss startups have been able to quickly scale their businesses and compete globally. Ava, a digital women’s health startup (acquired by FemTec Health) with offices in Zurich, San Francisco, Makati, and Belgrade, is all in on AWS. They created the Ava Fertility Tracker as a daily companion for women, which provides women with real-time, personalized information about fertility, pregnancy, and general health. The Ava bracelet is now sold in 36 countries worldwide and has been running on AWS since the first sales day.

Extending Reach through AWS Partner Network
Switzerland-based AWS Partner Network (APN) Partners also welcomed the news of the launch of the Europe (Zurich) Region.

The APN includes tens of thousands of independent software vendors (ISVs) and systems integrators (SIs) around the world. AWS SIs, consulting partners, and ISVs help enterprise and public sector customers migrate to AWS, deploy mission-critical applications, and provide a full range of services for your cloud environments. We have more than 150 partners ready to help you in Switzerland, one third of them have their headquarters in the country.

Promoting a Diverse Community of Professionals
In December 2020, Amazon announced that it will help 29 million people around the world grow their technological skills with free cloud computing skills training by 2025. Switzerland is part of this global effort. Since 2019, AWS and our AWS training partner Digicomp have delivered training and certification programs to individual learners, customers, and AWS Partners to rapidly build cloud skills and close the skills gap.

Several universities in Switzerland have delivered AWS Academy courses as part of their curriculum, including FHNW (Fachhochschule Nordwestschweiz), Fachhochschule Luzern, and Technische Berufsschule Zürich. To date, 32 Swiss institutions participated in the AWS Academy program, and 16 of them offered classes in 2022.

In March 2022, AWS launched AWS re/Start in Switzerland in collaboration with Powerhouse Lausanne, a training provider that promotes digital equality and diversity in Switzerland. A second cohort of AWS re/Start began in October 2022 in collaboration with the non profit Powercoders, which is focused on teaching IT skills specifically to refugees and helping them transition into the Swiss labor market.

Available Today
With the launch of the Europe (Zurich) Region, AWS is further expanding its infrastructure offering, empowering you with the flexibility to run applications on the most secure and reliable cloud infrastructure while maintaining local data residency and providing the lowest possible latency for Swiss end-users. The new Region is available today on the AWS Management Console and for your API calls.
Europe (Zurich) Region

Go and deploy your workloads on eu-central-2 today!

— seb

Introducing AWS Resource Explorer – Quickly Find Resources in Your AWS Account

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/introducing-aws-resource-explorer-quickly-find-resources-in-your-aws-account/

Looking for a specific Amazon Elastic Compute Cloud (Amazon EC2) instance, Amazon Elastic Container Service (Amazon ECS) task, or Amazon CloudWatch log group can take some time, especially if you have many resources and use multiple AWS Regions.

Today, we’re making that easier. Using the new AWS Resource Explorer, you can search through the AWS resources in your account across Regions using metadata such as names, tags, and IDs. When you find a resource in the AWS Management Console, you can quickly go from the search results to the corresponding service console and Region to start working on that resource. In a similar way, you can use the AWS Command Line Interface (CLI) or any of the AWS SDKs to find resources in your automation tools.

Let’s see how this works in practice.

Using AWS Resource Explorer
To start using Resource Explorer, I need to turn it on so that it creates and maintains the indexes that will provide fast responses to my search queries. Usually, the administrator of the account is the one taking these steps so that authorized users in that account can start searching.

To run a query, I need a view that gives access to an index. If the view is using an aggregator index, then the query can search across all indexed Regions.

Aggregator index diagram.

If the view is using a local index, then the query has access only to the resources in that Region.

Local index diagram.

I can control the visibility of resources in my account by creating views that define what resource information is available for search and discovery. These controls are not based only on resources but also on the information that resources bring. For example, I can give access to the Amazon Resource Names (ARNs) of all resources but not to their tags which might contain information that I want to keep confidential.

In the Resource Explorer console, I choose Enable Resource Explorer. Then, I select the Quick setup option to have visibility for all supported resources within my account. This option creates local indexes in all Regions and an aggregator index in the selected Region. A default view with a filter that includes all supported resources in the account is also created in the same Region as the aggregator index.

Console screenshot.

With the Advanced setup option, I have access to more granular controls that are useful when there are specific governance requirements. For example, I can select in which Regions to create indexes. I can choose not to replicate resource information to any other Region so that resources from each AWS Region are searchable only from within the same Region. I can also control what information is available in the default view or avoid the creation of the default view.

With the Quick setup option selected, I choose Go to Resource Explorer. A quick overview shows the progress of enabling Resource Explorer across Regions. After the indexes have been created, it can take up to 36 hours to index all supported resources, and search results might be incomplete until then. When resources are created or deleted, your indexes are automatically updated. These updates are asynchronous, so it can take some time (usually a few minutes) to see the changes.

Searching With AWS Resource Explorer
After resources have been indexed, I choose Proceed to resource search. In the Search criteria, I choose which View to use. Currently, I have the default view selected. Then, I start typing in the Query field to search through the resources in my AWS account across all Regions. For example, I have an application where I used the convention to start resource names with my-app. For the resources I created manually, I also added the Project tag with value MyApp.

To find the resource of this application, I start by searching for my-app.

Console screenshot.

The results include resources from multiple services and Regions and global resources from AWS Identity and Access Management (IAM). I have a service, tasks, and a task definition from Amazon ECS, roles and policies from AWS IAM, log groups from CloudWatch. Optionally, I can filter results by Region or resource type. If I choose any of the listed resources, the link will bring me to the corresponding service console and Region with the resource selected.

Console screenshot.

To look for something in a specific Region, such as Europe (Ireland), I can restrict the results by adding region:eu-west-1 to the query.

Console screenshot.

I can further restrict results to Amazon ECS resources by adding service:ecs to the query. Now I only see the ECS cluster, service, tasks, and task definition in Europe (Ireland). That’s the task definition I was looking for!

Console screenshot.

I can also search using tags. For example, I can see the resources where I added the MyApp tag by including tag.value:MyApp in a query. To specify the actual key-value pair of the tag, I can use tag:Project=MyApp.

Console screenshot.

Creating a Custom View
Sometimes you need to control the visibility of the resources in your account. For example, all the EC2 instances used for development in my account are in US West (Oregon). I create a view for the development team by choosing a specific Region (us-west-2) and filtering the results with service:ec2 in the query. Optionally, I could further filter results based on resource names or tags. For example, I could add tag:Environment=Dev to only see resources that have been tagged to be in a development environment.

Console screenshot.

Now I allow access to this view to users and roles used by the development team. To do so, I can attach an identity-based policy to the users and roles of the development team. In this way, they can only explore and search resources using this view.

Console screenshot.

Unified Search in the AWS Management Console
After I turn Resource Explorer on, I can also search through my AWS resources in the search bar at the top of the Management Console. We call this capability unified search as it gives results that include AWS services, features, blogs, documentation, tutorial, events, and more.

To focus my search on AWS resources, I add /Resources at the beginning of my search.

Console screenshot.

Note that unified search automatically inserts a wildcard character (*) at the end of the first keyword in the string. This means that unified search results include resources that match any string that starts with the specified keyword.

Console screenshot.

The search performed by the Query text box on the Resource search page in the Resource Explorer console does not automatically append a wildcard character but I can do it manually after any term in the search string to have similar results.

Unified search works when I have the default view in the same Region that contains the aggregator index. To check if unified search works for me, I look at the top of the Settings page.

Console screenshot.

Availability and Pricing
You can start using AWS Resource Explorer today with a global console and via the AWS Command Line Interface (CLI) and the AWS SDKs. AWS Resource Explorer is available at no additional charge. Using Resource Explorer makes it much faster to find the resources you need and use them in your automation processes and in their service console.

Discover and access your AWS resources across all the Regions you use with AWS Resource Explorer.

— Danilo

The collective thoughts of the interwebz