Tag Archives: serverless

AWS Lambda: Resilience under-the-hood

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/compute/aws-lambda-resilience-under-the-hood/

This post is written by Adrian Hornsby (Principal System Dev Engineer) and Marcia Villalba (Principal Developer Advocate).

AWS Lambda comprises over 80 services working together to provide the serverless compute service that it offers to customers. Under the hood, many of these services are built on top of Amazon Elastic Compute Cloud (Amazon EC2) instances, provisioned within Availability Zones. However, AWS Lambda is a Regional service. This means that customers use Lambda services from the Region level and its services are designed to be resilient to impairments that the underlying Availability Zones might have.

This blog post discusses how a Regional service such as Lambda takes advantage of Availability Zones and static stability to achieve its high availability target, and shows how Lambda teams verify their service’s static stability using AWS Fault Injection Simulator (AWS FIS). It also provides a solution using AWS services and tools to achieve Lambda’s resiliency strategy, using FIS, Amazon CloudWatch, and Amazon Route 53 Application Recovery Controller (Route 53 ARC).

The role of Availability Zones

Availability Zones are physically isolated sections of an AWS Region, designed to operate but also fail independently. They are separated by a meaningful distance from each other, up to 100 kilometers (60 miles), to prevent correlated failures, but close enough to use synchronous replication with single-digit millisecond latency.

Customers and AWS services have been using Availability Zones for years to build highly available, fault tolerant, and scalable applications. In particular, AWS Regional services such as AWS Lambda, Amazon DynamoDB, Amazon Simple Queue Service (Amazon SQS), and Amazon Simple Storage Service (Amazon S3), have achieved their high availability promises by spreading multiple independent replicas of their services across multiple Availability Zones. It uses the principles of independence and redundancy of Availability Zones to maximize the overall availability of that service.

Each replica is called a zonal replica. The system is designed so that any of the replicas can fail at any time. When a replica fails, it can be temporarily removed from the system until everything works as expected again. When that happens, the load is shared between the remaining zonal replicas.

Designing for failures

One lesson we learned at AWS when building services is when there is an Availability Zone impairment, it is better not to rely on control plane operations to remediate the failure. A control plane operation can, for example, be provisioning more capacity in an Availability Zone that is not affected by the impairment.

This principle is called static stability, and it describes the capability for a system to keep its original steady-state (or behavior) even when subjected to disruptive events without having to make any changes. A statically stable service should have as few dependencies as possible for its recovery process.

For a Regional service like AWS Lambda, this means that the remaining capacity in the healthy Availability Zones can absorb the traffic from a potentially impaired Availability Zone without having to scale up. This implies over-provisioning resources in all Availability Zones. Having that extra capacity pre-provisioned helps Lambda achieve its static stability. It is a tradeoff between the cost of over-provisioning resources and service availability. Since AWS Lambda promises high availability to its customers, with a monthly uptime service commitment of 99.95%, that tradeoff falls towards service availability.

How to prepare for failures

Preparing for an Availability Zone impairment is difficult because the symptoms and size of the impact can vary widely. An Availability Zone may be partially accessible or totally unreachable, and everything in between. Causes for the impairment can range from fiber cuts, power issues, overheating, hardware malfunctions, networking problems, capacity issues, and other unexpected situations. While those happen, they happen rarely. The most common categories of failures are bad deployments and bad configurations.

While some of these failures can be difficult to infer or reproduce, common symptoms include disruption of connectivity, increased latency, increased traffic due to retry storms, increased CPU and memory usage, and slow I/O.

At AWS, we learned to expect the unexpected and plan for failure. This means injecting faults in the system to reproduce some of the common symptoms of Availability Zone impairments, then observe how the system responds, and implement improvements. In addition, injecting faults in the system helps uncover potential monitoring and alarming blind spots, and gives an opportunity for teams to practice and improve their response to events with a focus on reducing time to recovery.

How Lambda tests its response to an Availability Zone impairment

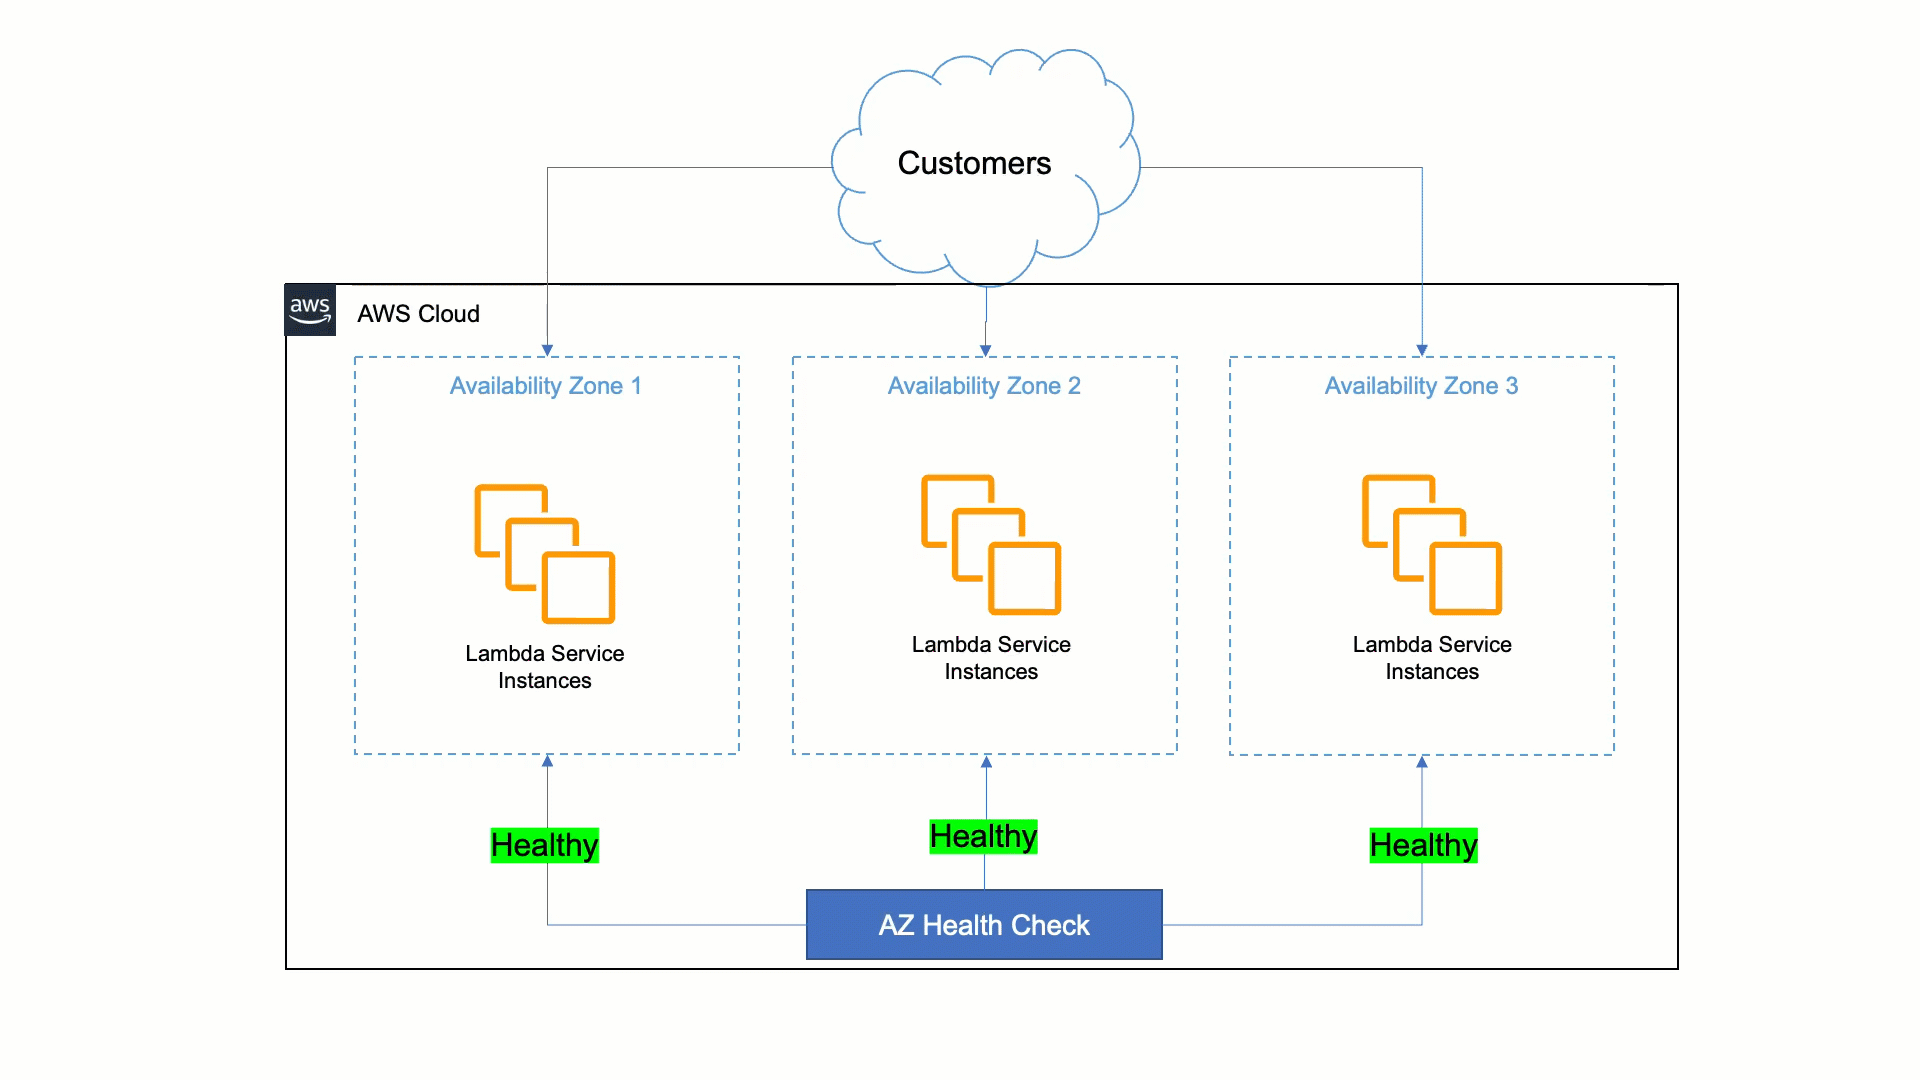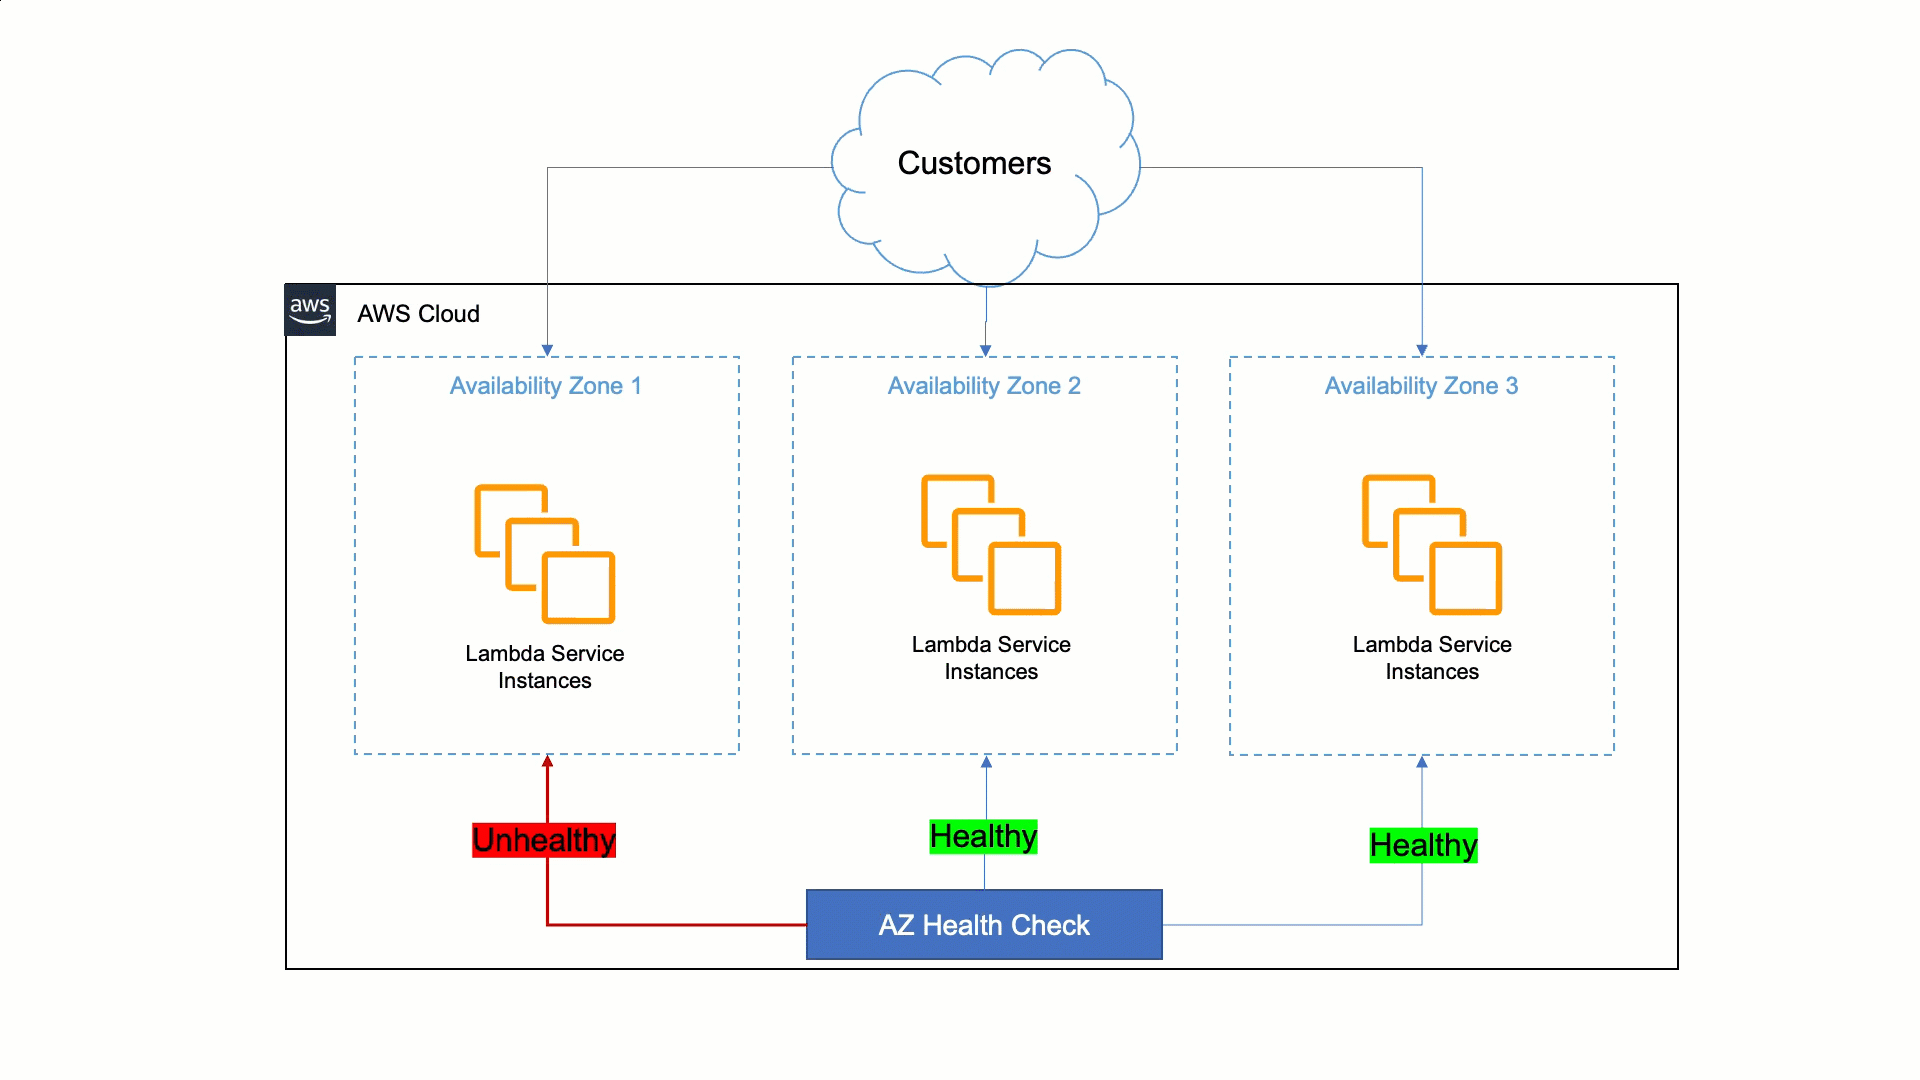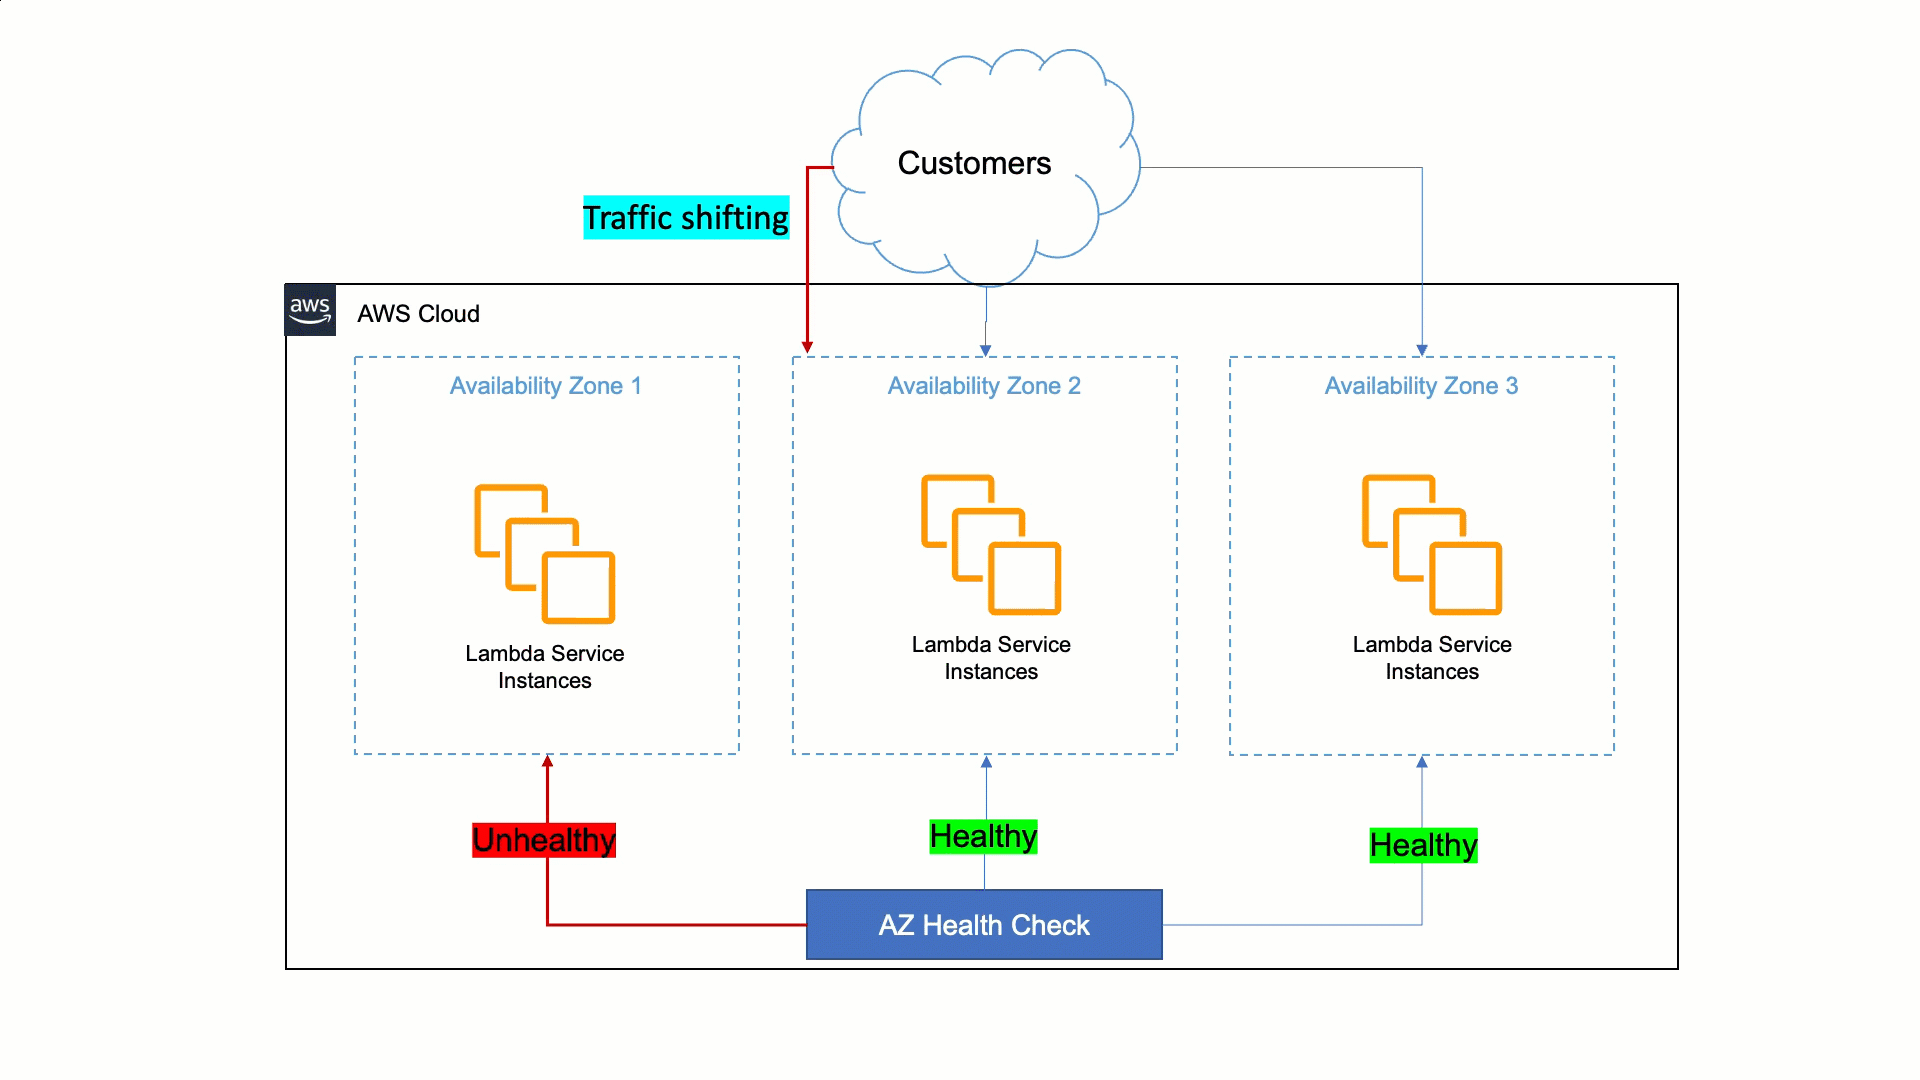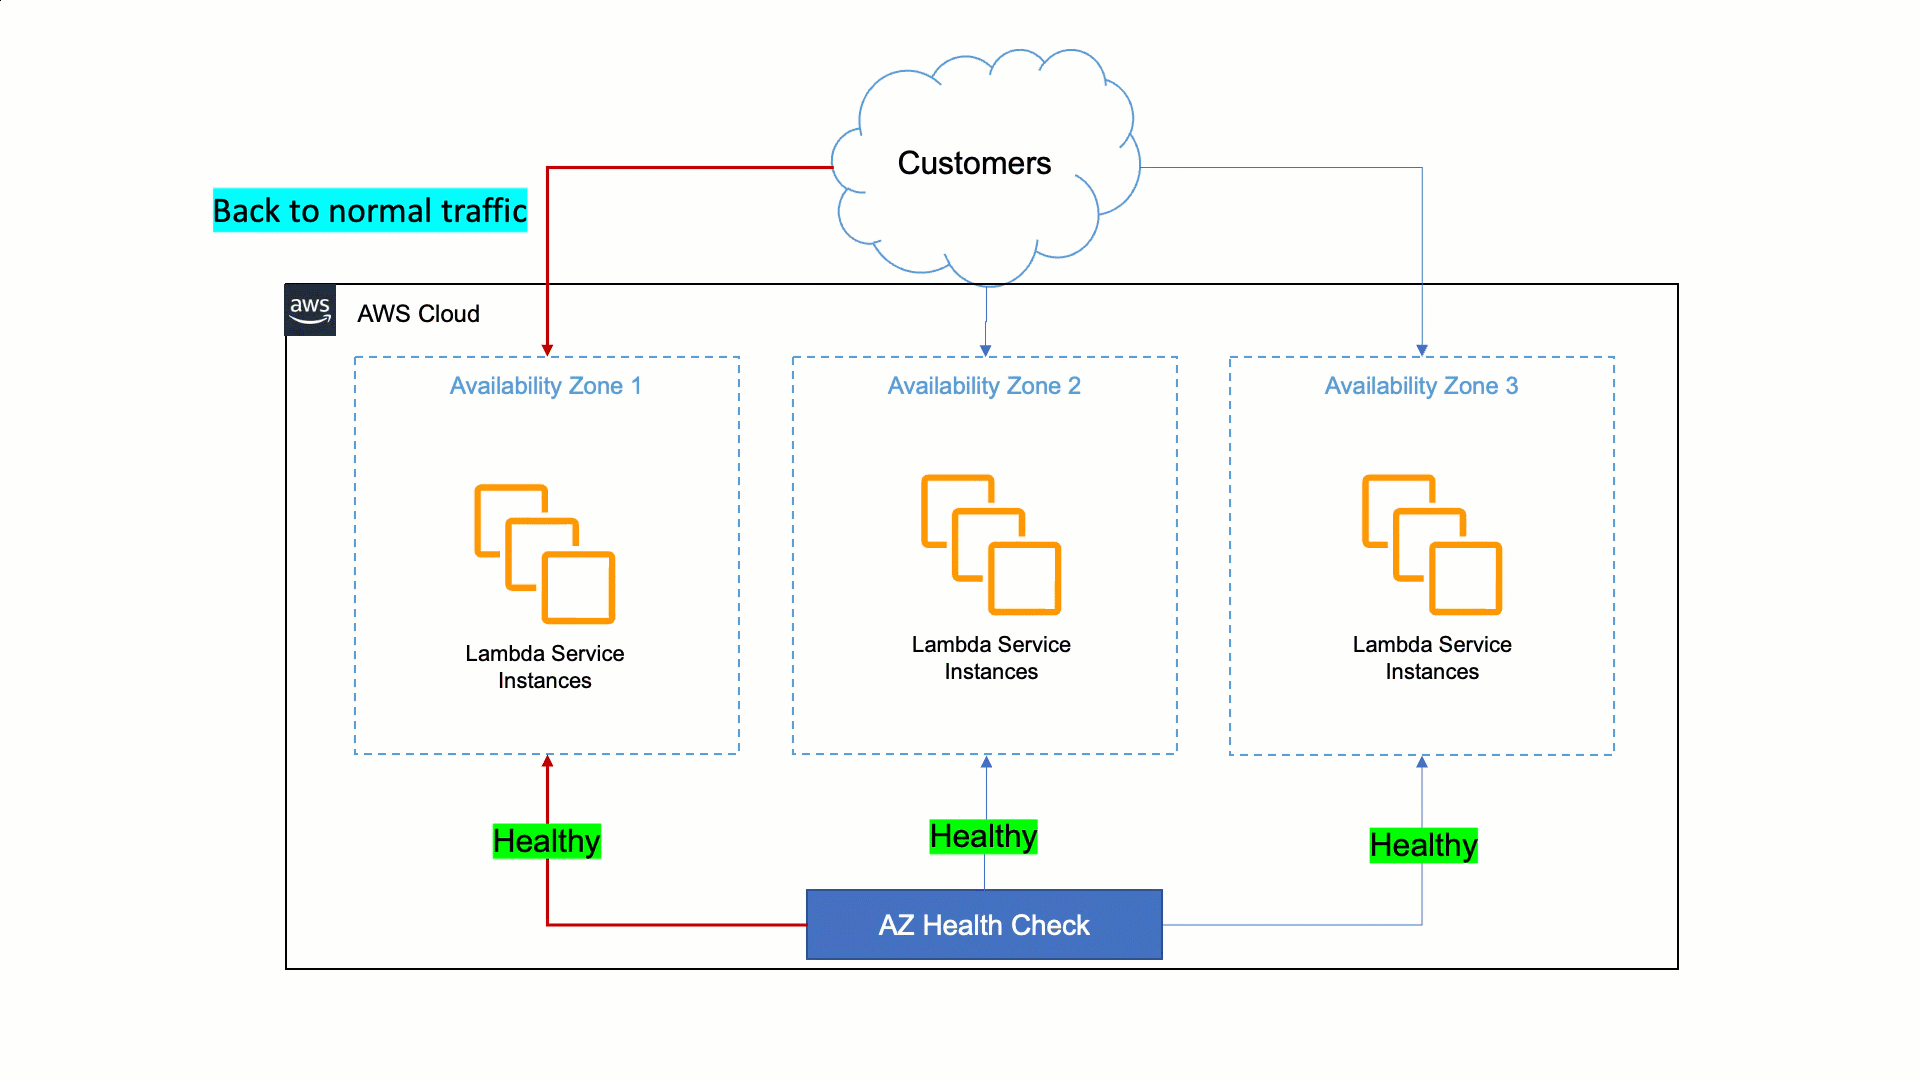
Lambda’s approach to being resilient to Availability Zone impairments is to rely on static stability and automated systems. Humans are slower than machines for detecting issues and mitigating them. Therefore, Lambda must ensure that its services can detect issues within a zonal replica and remediate automatically within minutes and with no operator intervention. This auto-remediation is done by shifting customer traffic away from the affected Availability Zone to healthy ones, and it is called Availability Zone evacuation.

To do this, Lambda built a tool that detects failures and performs the Availability Zone evacuation when needed. This tool does a statistical comparison of metrics between different Availability Zones and EC2 instances in order to identify unhealthy Availability Zones. If an Availability Zone is found to have issues, the tool starts the evacuation out of the unhealthy Availability Zone automatically. This automation cuts the time to the first action from 30 minutes to less than 3 minutes.

How AWS Lambda uses AWS FIS

To verify the automation continuously works as expected, Lambda performs a wide variety of tests, which includes Availability Zone failure testing in their pre-production environment. The main objective of these tests is to verify the services are statically stable in the presence of Availability Zone impairments, and to verify that the Availability Zone evacuation can be successfully initiated. The benefit of having an automated test is that teams can repeat it regularly and don’t need to have special skills. One click is all it takes to launch the test.

For these tests, Lambda uses AWS FIS to inject faults into their large fleet of EC2 instances. They use AWS FIS with support of the AWS System Manager (SSM) agent and resource filters to target their fleet of EC2 instances in a particular Availability Zone. This is a versatile approach that can inject resource faults, such as CPU and memory exhaustion, and networking faults, such as packet latency, loss, or drop.

Injecting packet loss or latency is very important, since these symptoms can have a serious impact on application and network performance. Indeed, latency and loss, even in small quantities, can create inefficiencies and prevent applications from running at their peak performance. For Lambda, being able to detect increased latency or loss before it affects customers is critical.

How to recover your applications rapidly from Availability Zones failures

You can build a similar solution to rapidly recover your applications from a zonal failure. The solution must have a mechanism to evacuate an impaired Availability Zone, a monitoring system that allows you to detect when a zonal replica is impaired, and a way to test the static stability of your system. AWS provides many tools and services that can help you build this solution to achieve Lambda’s resiliency strategy.

For performing Availability Zone evacuation, you can use the new zonal shift capability from Route 53 ARC, which at the time of writing is in preview. Zonal shift lets you evacuate an Availability Zone for applications that are uses Elastic Load Balancing. If you find out that a zonal replica is impaired or unhealthy, you can use zonal shift to evacuate the Availability Zone for a period of time, while the issue gets fixed.

For performing the zonal shift, you must detect when a zonal replica is unhealthy. Your application must provide a signal of its health per Availability Zone. There are two common ways to capture this signal. First, passively, you can check your metrics, like response times, HTTP status codes, and other metrics that can help track fatal errors in your applications. Or actively, using synthetic monitoring, which allows you to create synthetic requests against your production application to provide a more complete view of the customer experience.

Amazon CloudWatch Synthetics provides canaries, which are scripts that run on a schedule and perform synthetic requests in your application endpoints and APIs. Canaries perform the same actions as customers and continuously verify the customer experience. You can create a canary for each zonal replica of your application and monitor the results independently.

With this information, if the user experience diminishes in one of the replicas, you can start an Availability Zone evacuation using zonal shift and minimize the bad experience for the user while you find and fix the sources of the failure.

To ensure that you can successfully recover from a failure, you must test the solution in advance. Without testing, it is just an assumption. To prove or disprove your assumptions about your system’s capability to handle disruptive events such as issues within an Availability Zones, you can use FIS.

With FIS, you can inject faults simultaneously in multiple resources within the same failure domain, such as Availability Zones. FIS currently integrates with several AWS services including EC2, Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Elastic Container Service (Amazon ECS), Amazon Relational Database Service (Amazon RDS), AWS Networking, and CloudWatch.

Typical use cases for testing a workload’s resilience to Availability Zones impairment are, for example, terminating all compute resources and databases within a particular Availability Zone, injecting latency or packet loss, increasing resource consumption (CPU, memory, and I/O) in compute resources in a particular Availability Zone, or impacting network communication within or between Availability Zones.

For more information and a step-by-step example of how to recover rapidly from application failures in a single Availability Zone and testing it with AWS FIS, read this blog post.

Conclusion

­­­This article discusses static stability, a mechanism that is used by AWS services such as Lambda to build resilient Regional services. It also discusses how AWS takes advantage of the same services and infrastructure as customers. It shows how Lambda uses multiple Availability Zones and services like AWS FIS to build highly available services and improve its recovery time from unexpected failures to only a few minutes without human intervention. Finally, it shows a solution that you can implement for your applications to achieve Lambda’s resilience strategy.

To learn more about AWS FIS, there are many tutorials and a workshop you can check out.

For more serverless learning resources, visit Serverless Land.

Processing geospatial IoT data with AWS IoT Core and the Amazon Location Service

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/compute/processing-geospatial-iot-data-with-aws-iot-core-and-the-amazon-location-service/

This post is written by Swarna Kunnath (Cloud Application Architect), and Anand Komandooru (Sr. Cloud Application Architect).

This blog post shows how to republish messages that arrive from Internet of Things (IoT) devices across AWS accounts using a replatforming approach. A replatforming approach minimizes changes to the core application architecture, allowing an organization to reduce risk and meet business needs more quickly. In this post, you also learn how to track an IoT device’s location using the Amazon Location Service.

The example used in this post relates to an aviation company that has airplanes with line replacement unit devices or transponders. Transponders are IoT devices that send airplane geospatial data (location and altitude) to the AWS IoT Core service. The company’s airplane transponders send location data to the AWS IoT Core service provisioned in an existing AWS account (source account). The solution required manual intervention to track airplane location sent by the transponders.

They must rearchitect their application due to an internal reorganization event. As part of the rearchitecture approach, the business decides to enhance the application to process the transponder messages in another AWS account (destination account). In addition, the business needs full automation of the airplane’s location tracking process, to minimize the risk of the application changes, and to deliver the changes quickly.

Solution overview

The high-level solution republishes the IoT messages from the source account to the destination account using AWS IoT Core, Amazon SQS, AWS Lambda, and integrates the application with Amazon Location Service. IoT messages are replicated to an IoT topic in the destination account for downstream processing, minimizing changes to the original application architecture. Integration with Amazon Location Service automates the process of device location tracking and alert generation.

The AWS IoT platform allows you to connect your internet-enabled devices to the AWS Cloud via MQTT, HTTP, or WebSocket protocol. Once connected, the devices send data to the MQTT topics. Data ingested on MQTT topics is routed into AWS services (Amazon S3, SQS, Amazon DynamoDB, and Lambda) by configuring rules in the AWS IoT Rules Engine. The AWS IoT Rules Engine offers ways to define queries to format and filter messages published by these devices, and supports integration with several other AWS services as targets.

The Amazon Location Service lets you add geospatial data including capabilities such as maps, points of interest, geocoding, routing, geofences, and tracking. The tracker with geofence tracks the location of the device based on the geospatial data in the published IoT messages. Amazon Location Service generates enter and exit events and integrates with Amazon EventBridge and Amazon Simple Notification Service (Amazon SNS) to generate alerts based on defined filters in EventBridge rules.

The solution in this post delivers high availability, scalability, and cost efficiency by using serverless and managed services. The serverless services used by this solution also provide automatic scaling and built-in high availability. Integrating Amazon Location Service with AWS IoT and EventBridge helps to automate the auditing and processing of geospatial messages.

Solution architecture

These steps describe an end-to-end sequence of events:

  1. An IoT device (a transponder in an airplane) publishes a message to the AWS IoT Core service in the source account.
  2. The message arrives at an AWS IoT Core topic in the source account.
  3. AWS IoT Rules Engine receives the message and processes it, using IoT rules attached to the corresponding topic in the source account.
  4. An AWS IoT rule replicates the message to an SQS queue in the destination account.
  5. A Lambda function in the destination account polls the SQS queue and publishes received messages in batches to the destination account IoT topic.
  6. The Location action configured to the IoT rule sends the messages to Amazon Location Service tracker from the IoT topic.
  7. An Amazon Location tracker sends events when an IoT device enters or exits a linked geofence.
  8. EventBridge receives these events and, via the configured event rule, sends out SNS notifications for the configured devices.

Pre-requisites

This example has the following prerequisites:

  1. Access to the AWS services mentioned in this blog post within two AWS Accounts.
  2. A local install of AWS SAM CLI to build and deploy the sample code.

Solution walkthrough

To deploy this solution, first deploy IoT components via the AWS Serverless Application Model (AWS SAM), in the source and destination accounts. After, configure Amazon Location Service resources in the destination account. To learn more, visit the AWS SAM deployment documentation.

Deploying the code

Deploy the following AWS SAM templates in order:

To build and deploy the code, run:

sam build --template <TemplateName>.yaml
sam deploy --guided

Configuring a tracker

Amazon Location Trackers send device location updates that provide data to retrieve current and historical locations for devices.

Using Amazon Location Trackers and Amazon Location Geofences together, you can automatically evaluate the location updates from your IoT devices against your geofences to generate the geofence events. Actions could be taken to generate the alerts based on the areas of interest.

  1. Follow the instructions in the documentation to create the tracker resource from the AWS Management Console. Use this information for the new tracker:
    • Name: Enter a unique name that has a maximum of 100 characters. For example, FlightTracker.
    • Description: Enter an optional description. For example, Tracker for storing device positions.
  2. Configure a Location action to the destination IoT rule that receives messages from the destination IoT topic and publishes them in batches to the configured Tracker device (for example, FlightTracker). The parameters in the JSON data that is returned to the Location action can also be configured via substitution templates.

Geofence collection

Geofences contain points and vertices that form a closed boundary, which defines an area of interest. For example, flight origin and destination details. You can use tools, such as GeoJSON.io, to draw geofences and save the output as a GeoJSON file. Follow the instructions in the documentation to create the GeoJSON file and link it to the geofence collection.

  1. Create the geofence collection with a GeoJSON file and link it to the tracker you just created.
  2. Link the tracker to the geofence by following these instructions and start tracking the device’s location updates. You can link them together so that you automatically evaluate location updates against all your geofences. You can evaluate device positions against geofences on demand as well.

When device positions are evaluated against geofences, they generate events. For example, when a plane enters or exits a location specified in the geofence.

You can configure EventBridge with rules to react to these events. You can set up SNS to notify your clients when a specific tracker device location changes. Follow the instructions in the documentation on how to set up EventBridge rules to integrate with Amazon Location Service events.

Testing the solution

You can test the first part of the solution by sending an IoT message with location details in the JSON format from the source account and verify that the message arrives at the destination account SQS queue. Detailed instructions to publish a test message from the source account that includes location information (latitude and longitude) can be found here.

Messages from the destination account SQS queue are published to the Amazon Location Service Tracker. When the location in the test message matches the criteria provided in the geofence, Amazon Location Service generates an event. EventBridge has a rule configured that gets matched when an Amazon Location tracker event arrives, and the rule target is an SNS topic that sends an email or text message to the client.

Cleaning up

To avoid incurring future charges, delete the CloudFormation stacks, location tracker, and geofence collection created as part of the solution walk-through. Replace the resource identifiers in the following commands with the ID/name of the resources.

  1. Delete the SAM application stack:
    aws cloudformation delete-stack --stack-name <StackName>
    

    Refer to this documentation for further information.

  2. Delete the location tracker:
    aws location delete-tracker --tracker-name <TrackerName>
  3. Delete the geofence collection:
    aws location delete-geofence-collection --collection-name <GeoCollectionName>

Conclusion

This blog post shows how to create a serverless solution for cross account IoT message publishing and tracking device location updates using Amazon Location Service.

It describes the process of how to publish AWS IoT messages across multiple accounts. Integration with the Amazon Location Service shows how to track IoT device location updates and generate alerts, alleviating the need for manual device location tracking.

For more serverless learning resources, visit Serverless Land.

Introducing maximum concurrency of AWS Lambda functions when using Amazon SQS as an event source

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/introducing-maximum-concurrency-of-aws-lambda-functions-when-using-amazon-sqs-as-an-event-source/

This blog post is written by Solutions Architects John Lee and Jeetendra Vaidya.

AWS Lambda now provides a way to control the maximum number of concurrent functions invoked by Amazon SQS as an event source. You can use this feature to control the concurrency of Lambda functions processing messages in individual SQS queues.

This post describes how to set the maximum concurrency of SQS triggers when using SQS as an event source with Lambda. It also provides an overview of the scaling behavior of Lambda using this architectural pattern, challenges this feature helps address, and a demo of the maximum concurrency feature.

Overview

Lambda uses an event source mapping to process items from a stream or queue. The event source mapping reads from an event source, such as an SQS queue, optionally filters the messages, batches them, and invokes the mapped Lambda function.

The scaling behavior for Lambda integration with SQS FIFO queues is simple. A single Lambda function processes batches of messages within a single message group to ensure that messages are processed in order.

For SQS standard queues, the event source mapping polls the queue to consume incoming messages, starting at five concurrent batches with five functions at a time. As messages are added to the SQS queue, Lambda continues to scale out to meet demand, adding up to 60 functions per minute, up to 1,000 functions, to consume those messages. To learn more about Lambda scaling behavior, read ”Understanding how AWS Lambda scales with Amazon SQS standard queues.”

Lambda processing standard SQS queues

Lambda processing standard SQS queues

Challenges

When a large number of messages are in the SQS queue, Lambda scales out, adding additional functions to process the messages. The scale out can consume the concurrency quota in the account. To prevent this from happening, you can set reserved concurrency for individual Lambda functions. This ensures that the specified Lambda function can always scale to that much concurrency, but it also cannot exceed this number.

When the Lambda function concurrency reaches the reserved concurrency limit, the queue configuration specifies the subsequent behavior. The message is returned to the queue and retried based on the redrive policy, expired based on its retention policy, or sent to another SQS dead-letter queue (DLQ). While sending unprocessed messages to a DLQ is a good option to preserve messages, it requires a separate mechanism to inspect and process messages from the DLQ.

The following example shows a Lambda function reaching its reserved concurrency quota of 10.

Lambda reaching reserved concurrency of 10.

Lambda reaching reserved concurrency of 10.

Maximum Lambda concurrency with SQS as an event source

The launch of maximum concurrency for SQS as an event source allows you to control Lambda function concurrency per source. You set the maximum concurrency on the event source mapping, not on the Lambda function.

This event source mapping setting does not change the scaling or batching behavior of Lambda with SQS. You can continue to batch messages with a customized batch size and window. It rather sets a limit on the maximum number of concurrent function invocations per SQS event source. Once Lambda scales and reaches the maximum concurrency configured on the event source, Lambda stops reading more messages from the queue. This feature also provides you with the flexibility to define the maximum concurrency for individual event sources when the Lambda function has multiple event sources.

Maximum concurrency is set to 10 for the SQS queue.

Maximum concurrency is set to 10 for the SQS queue.

This feature can help prevent a Lambda function from consuming all available Lambda concurrency of the account and avoids messages returning to the queue unnecessarily because of Lambda functions being throttled. It provides an easier way to control and consume messages at a desired pace, controlled by the maximum number of concurrent Lambda functions.

The maximum concurrency setting does not replace the existing reserved concurrency feature. Both serve distinct purposes and the two features can be used together. Maximum concurrency can help prevent overwhelming downstream systems and unnecessary throttled invocations. Reserved concurrency guarantees a maximum number of concurrent instances for the function.

When used together, the Lambda function can have its own allocated capacity (reserved concurrency), while being able to control the throughput for each event source (maximum concurrency). When using the two features together, you must set the function reserved concurrency higher than the maximum concurrency on the SQS event source mapping to prevent throttling.

Setting maximum concurrency for SQS as an event source

You can configure the maximum concurrency for an SQS event source through the AWS Management Console, AWS Command Line Interface (CLI), or infrastructure as code tools such as AWS Serverless Application Model (AWS SAM). The minimum supported value is 2 and the maximum value is 1000. Refer to the Lambda quotas documentation for the latest limits.

Configuring the maximum concurrency for an SQS trigger in the console

Configuring the maximum concurrency for an SQS trigger in the console

You can set the maximum concurrency through the create-event-source-mapping AWS CLI command.

aws lambda create-event-source-mapping --function-name my-function --ScalingConfig {MaxConcurrency=2} --event-source-arn arn:aws:sqs:us-east-2:123456789012:my-queue

Seeing the maximum concurrency setting in action

The following demo compares Lambda receiving and processes messages differently when using maximum concurrency compared to reserved concurrency.

This GitHub repository contains an AWS SAM template that deploys the following resources:

  • ReservedConcurrencyQueue (SQS queue)
  • ReservedConcurrencyDeadLetterQueue (SQS queue)
  • ReservedConcurrencyFunction (Lambda function)
  • MaxConcurrencyQueue (SQS queue)
  • MaxConcurrencyDeadLetterQueue (SQS queue)
  • MaxConcurrencyFunction (Lambda function)
  • CloudWatchDashboard (CloudWatch dashboard)

The AWS SAM template provisions two sets of identical architectures and an Amazon CloudWatch dashboard to monitor the resources. Each architecture comprises a Lambda function receiving messages from an SQS queue, and a DLQ for the SQS queue.

The maxReceiveCount is set as 1 for the SQS queues, which sends any returned messages directly to the DLQ. The ReservedConcurrencyFunction has its reserved concurrency set to 5, and the MaxConcurrencyFunction has the maximum concurrency for the SQS event source set to 5.

Pre-requisites

Running this demo requires the AWS CLI and the AWS SAM CLI. After installing both CLIs, clone this GitHub repository and navigate to the root of the directory:

git clone https://github.com/aws-samples/aws-lambda-amazon-sqs-max-concurrency
cd aws-lambda-amazon-sqs-max-concurrency

Deploying the AWS SAM template

  1. Build the AWS SAM template with the build command to prepare for deployment to your AWS environment.
  2. sam build
  3. Use the guided deploy command to deploy the resources in your account.
  4. sam deploy --guided
  5. Give the stack a name and accept the remaining default values. Once deployed, you can track the progress through the CLI or by navigating to the AWS CloudFormation page in the AWS Management Console.
  6. Note the queue URLs from the Outputs tab in the AWS SAM CLI, CloudFormation console, or navigate to the SQS console to find the queue URLs.
The Outputs tab of the launched AWS SAM template provides URLs to CloudWatch dashboard and SQS queues.

The Outputs tab of the launched AWS SAM template provides URLs to CloudWatch dashboard and SQS queues.

Running the demo

The deployed Lambda function code simulates processing by sleeping for 10 seconds before returning a 200 response. This allows the function to reach a high function concurrency number with only a small number of messages.

To add 25 messages to the Reserved Concurrency queue, run the following commands. Replace <ReservedConcurrencyQueueURL> with your queue URL from the AWS SAM Outputs.

for i in {1..25}; do aws sqs send-message --queue-url <ReservedConcurrencyQueueURL> --message-body testing; done 

To add 25 messages to the Maximum Concurrency queue, run the following commands. Replace <MaxConcurrencyQueueURL> with your queue URL from the AWS SAM Outputs.

for i in {1..25}; do aws sqs send-message --queue-url <MaxConcurrencyQueueURL> --message-body testing; done 

After sending messages to both queues, navigate to the dashboard URL available in the Outputs tab to view the CloudWatch dashboard.

Validating results

Both Lambda functions have the same number of invocations and the same concurrent invocations fixed at 5. The CloudWatch dashboard shows the ReservedConcurrencyFunction experienced throttling and 9 messages, as seen in the top-right metric, were sent to the corresponding DLQ. The MaxConcurrencyFunction did not experience any throttling and messages were not delivered to the DLQ.

CloudWatch dashboard showing throttling and DLQs.

CloudWatch dashboard showing throttling and DLQs.

Clean up

To remove all the resources created in this demo, use the delete command and follow the prompts:

sam delete

Conclusion

You can now control the maximum number of concurrent functions invoked by SQS as a Lambda event source. This post explains the scaling behavior of Lambda using this architectural pattern, challenges this feature helps address, and a demo of maximum concurrency in action.

There are no additional charges to use this feature besides the standard SQS and Lambda charges. You can start using maximum concurrency for SQS as an event source with new or existing event source mappings by connecting it with SQS. This feature is available in all Regions where Lambda and SQS are available.

For more serverless learning resources, visit Serverless Land.

Add your own libraries and application dependencies to Spark and Hive on Amazon EMR Serverless with custom images

Post Syndicated from Veena Vasudevan original https://aws.amazon.com/blogs/big-data/add-your-own-libraries-and-application-dependencies-to-spark-and-hive-on-amazon-emr-serverless-with-custom-images/

Amazon EMR Serverless allows you to run open-source big data frameworks such as Apache Spark and Apache Hive without managing clusters and servers. Many customers who run Spark and Hive applications want to add their own libraries and dependencies to the application runtime. For example, you may want to add popular open-source extensions to Spark, or add a customized encryption-decryption module that is used by your application.

We are excited to announce a new capability that allows you to customize the runtime image used in EMR Serverless by adding custom libraries that your applications need to use. This feature enables you to do the following:

  • Maintain a set of version-controlled libraries that are reused and available for use in all your EMR Serverless jobs as part of the EMR Serverless runtime
  • Add popular extensions to open-source Spark and Hive frameworks such as pandas, NumPy, matplotlib, and more that you want your EMR serverless application to use
  • Use established CI/CD processes to build, test, and deploy your customized extension libraries to the EMR Serverless runtime
  • Apply established security processes, such as image scanning, to meet the compliance and governance requirements within your organization
  • Use a different version of a runtime component (for example the JDK runtime or the Python SDK runtime) than the version that is available by default with EMR Serverless

In this post, we demonstrate how to use this new feature.

Solution Overview

To use this capability, customize the EMR Serverless base image using Amazon Elastic Container Registry (Amazon ECR), which is a fully managed container registry that makes it easy for your developers to share and deploy container images. Amazon ECR eliminates the need to operate your own container repositories or worry about scaling the underlying infrastructure. After the custom image is pushed to the container registry, specify the custom image while creating your EMR Serverless applications.

The following diagram illustrates the steps involved in using custom images for your EMR Serverless applications.

In the following sections, we demonstrate using custom images with Amazon EMR Serverless to address three common use cases:

  • Add popular open-source Python libraries into the EMR Serverless runtime image
  • Use a different or newer version of the Java runtime for the EMR Serverless application
  • Install a Prometheus agent and customize the Spark runtime to push Spark JMX metrics to Amazon Managed Service for Prometheus, and visualize the metrics in a Grafana dashboard

General prerequisites

The following are the prerequisites to use custom images with EMR Serverless. Complete the following steps before proceeding with the subsequent steps:

  1. Create an AWS Identity and Access Management (IAM) role with IAM permissions for Amazon EMR Serverless applications, Amazon ECR permissions, and Amazon S3 permissions for the Amazon Simple Storage Service (Amazon S3) bucket aws-bigdata-blog and any S3 bucket in your account where you will store the application artifacts.
  2. Install or upgrade to the latest AWS Command Line Interface (AWS CLI) version and install the Docker service in an Amazon Linux 2 based Amazon Elastic Compute Cloud (Amazon EC2) instance. Attach the IAM role from the previous step for this EC2 instance.
  3. Select a base EMR Serverless image from the following public Amazon ECR repository. Run the following commands on the EC2 instance with Docker installed to verify that you are able to pull the base image from the public repository:
    # If docker is not started already, start the process
    $ sudo service docker start 
    
    # Check if you are able to pull the latest EMR 6.9.0 runtime base image 
    $ sudo docker pull public.ecr.aws/emr-serverless/spark/emr-6.9.0:latest

  4. Log in to Amazon ECR with the following commands and create a repository called emr-serverless-ci-examples, providing your AWS account ID and Region:
    $ sudo aws ecr get-login-password --region <region> | sudo docker login --username AWS --password-stdin <your AWS account ID>.dkr.ecr.<region>.amazonaws.com
    
    $ aws ecr create-repository --repository-name emr-serverless-ci-examples --region <region>

  5. Provide IAM permissions to the EMR Serverless service principal for the Amazon ECR repository:
    1. On the Amazon ECR console, choose Permissions under Repositories in the navigation pane.
    2. Choose Edit policy JSON.
    3. Enter the following JSON and save:
      {
        "Version": "2012-10-17",
        "Statement": [
          {
            "Sid": "Emr Serverless Custom Image Support",
            "Effect": "Allow",
            "Principal": {
              "Service": "emr-serverless.amazonaws.com"
            },
            "Action": [
              "ecr:BatchGetImage",
              "ecr:DescribeImages",
              "ecr:GetDownloadUrlForLayer"
            ]
          }
        ]
      }

Make sure that the policy is updated on the Amazon ECR console.

For production workloads, we recommend adding a condition in the Amazon ECR policy to ensure only allowed EMR Serverless applications can get, describe, and download images from this repository. For more information, refer to Allow EMR Serverless to access the custom image repository.

In the next steps, we create and use custom images in our EMR Serverless applications for the three different use cases.

Use case 1: Run data science applications

One of the common applications of Spark on Amazon EMR is the ability to run data science and machine learning (ML) applications at scale. For large datasets, Spark includes SparkML, which offers common ML algorithms that can be used to train models in a distributed fashion. However, you often need to run many iterations of simple classifiers to fit for hyperparameter tuning, ensembles, and multi-class solutions over small-to-medium-sized data (100,000 to 1 million records). Spark is a great engine to run multiple iterations of such classifiers in parallel. In this example, we demonstrate this use case, where we use Spark to run multiple iterations of an XGBoost model to select the best parameters. The ability to include Python dependencies in the EMR Serverless image should make it easy to make the various dependencies (xgboost, sk-dist, pandas, numpy, and so on) available for the application.

Prerequisites

The EMR Serverless job runtime IAM role should be given permissions to your S3 bucket where you will be storing your PySpark file and application logs:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "AccessToS3Buckets",
            "Effect": "Allow",
            "Action": [
                "s3:PutObject",
                "s3:GetObject",
                "s3:ListBucket"
            ],
            "Resource": [
                "arn:aws:s3:::<YOUR-BUCKET>",
                "arn:aws:s3:::<YOUR-BUCKET>/*"
            ]
        }
    ]
}

Create an image to install ML dependencies

We create a custom image from the base EMR Serverless image to install dependencies required by the SparkML application. Create the following Dockerfile in your EC2 instance that runs the docker process inside a new directory named datascience:

FROM public.ecr.aws/emr-serverless/spark/emr-6.9.0:latest

USER root

# python packages
RUN pip3 install boto3 pandas numpy
RUN pip3 install -U scikit-learn==0.23.2 scipy 
RUN pip3 install sk-dist
RUN pip3 install xgboost
RUN sed -i 's|import Parallel, delayed|import Parallel, delayed, logger|g' /usr/local/lib/python3.7/site-packages/skdist/distribute/search.py

# EMRS will run the image as hadoop
USER hadoop:hadoop

Build and push the image to the Amazon ECR repository emr-serverless-ci-examples, providing your AWS account ID and Region:

# Build the image locally. This command will take a minute or so to complete
sudo docker build -t local/emr-serverless-ci-ml /home/ec2-user/datascience/ --no-cache --pull
# Create tag for the local image
sudo docker tag local/emr-serverless-ci-ml:latest <your AWS account ID>.dkr.ecr.<region>.amazonaws.com/emr-serverless-ci-examples:emr-serverless-ci-ml
# Push the image to Amazon ECR. This command will take a few seconds to complete
sudo docker push <your AWS account ID>.dkr.ecr.<region>.amazonaws.com/emr-serverless-ci-examples:emr-serverless-ci-ml

Submit your Spark application

Create an EMR Serverless application with the custom image created in the previous step:

aws --region <region>  emr-serverless create-application \
    --release-label emr-6.9.0 \
    --type "SPARK" \
    --name data-science-with-ci \
    --image-configuration '{ "imageUri": "<your AWS account ID>.dkr.ecr.<region>.amazonaws.com/emr-serverless-ci-examples:emr-serverless-ci-ml" }'

Make a note of the value of applicationId returned by the command.

After the application is created, we’re ready to submit our job. Copy the application file to your S3 bucket:

aws s3 cp s3://aws-bigdata-blog/artifacts/BDB-2771/code/emrserverless-xgboost-spark-example.py s3://<YOUR BUCKET>/<PREFIX>/emrserverless-xgboost-spark-example.py

Submit the Spark data science job. In the following command, provide the name of the S3 bucket and prefix where you stored your application file. Additionally, provide the applicationId value obtained from the create-application command and your EMR Serverless job runtime IAM role ARN.

aws emr-serverless start-job-run \
        --region <region> \
        --application-id <applicationId> \
        --execution-role-arn <jobRuntimeRole> \
        --job-driver '{
            "sparkSubmit": {
                "entryPoint": "s3://<YOUR BUCKET>/<PREFIX>/emrserverless-xgboost-spark-example.py"
            }
        }' \
        --configuration-overrides '{
              "monitoringConfiguration": {
                "s3MonitoringConfiguration": {
                  "logUri": "s3://<YOUR BUCKET>/emrserverless/logs"
                }
              }
            }'

After the Spark job succeeds, you can view the best model estimates from our application by viewing the Spark driver’s stdout logs. Navigate to Spark History Server, Executors, Driver, Logs, stdout.

Use case 2: Use a custom Java runtime environment

Another use case for custom images is the ability to use a custom Java version for your EMR Serverless applications. For example, if you’re using Java11 to compile and package your Java or Scala applications, and try to run them directly on EMR Serverless, it may lead to runtime errors because EMR Serverless uses Java 8 JRE by default. To make the runtime environments of your EMR Serverless applications compatible with your compile environment, you can use the custom images feature to install the Java version you are using to package your applications.

Prerequisites

An EMR Serverless job runtime IAM role should be given permissions to your S3 bucket where you will be storing your application JAR and logs:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "AccessToS3Buckets",
            "Effect": "Allow",
            "Action": [
                "s3:PutObject",
                "s3:GetObject",
                "s3:ListBucket"
            ],
            "Resource": [
                "arn:aws:s3:::<YOUR-BUCKET>",
                "arn:aws:s3:::<YOUR-BUCKET>/*"
            ]
        }
    ]
}

Create an image to install a custom Java version

We first create an image that will install a Java 11 runtime environment. Create the following Dockerfile in your EC2 instance inside a new directory named customjre:

FROM public.ecr.aws/emr-serverless/spark/emr-6.9.0:latest

USER root

# Install JDK 11
RUN amazon-linux-extras install java-openjdk11

# EMRS will run the image as hadoop
USER hadoop:hadoop

Build and push the image to the Amazon ECR repository emr-serverless-ci-examples, providing your AWS account ID and Region:

sudo docker build -t local/emr-serverless-ci-java11 /home/ec2-user/customjre/ --no-cache --pull
sudo docker tag local/emr-serverless-ci-java11:latest <your AWS account ID>.dkr.ecr.<region>.amazonaws.com/emr-serverless-ci-examples:emr-serverless-ci-java11
sudo docker push <your AWS account ID>.dkr.ecr.<region>.amazonaws.com/emr-serverless-ci-examples:emr-serverless-ci-java11

Submit your Spark application

Create an EMR Serverless application with the custom image created in the previous step:

aws --region <region>  emr-serverless create-application \
    --release-label emr-6.9.0 \
    --type "SPARK" \
    --name custom-jre-with-ci \
    --image-configuration '{ "imageUri": "<your AWS account ID>.dkr.ecr.<region>.amazonaws.com/emr-serverless-ci-examples:emr-serverless-ci-java11" }'

Copy the application JAR to your S3 bucket:

aws s3 cp s3://aws-bigdata-blog/artifacts/BDB-2771/code/emrserverless-custom-images_2.12-1.0.jar s3://<YOUR BUCKET>/<PREFIX>/emrserverless-custom-images_2.12-1.0.jar

Submit a Spark Scala job that was compiled with Java11 JRE. This job also uses Java APIs that may produce different results for different versions of Java (for example: java.time.ZoneId). In the following command, provide the name of the S3 bucket and prefix where you stored your application JAR. Additionally, provide the applicationId value obtained from the create-application command and your EMR Serverless job runtime role ARN with IAM permissions mentioned in the prerequisites. Note that in the sparkSubmitParameters, we pass a custom Java version for our Spark driver and executor environments to instruct our job to use the Java11 runtime.

aws emr-serverless start-job-run \
        --region <region> \
        --application-id <applicationId> \
        --execution-role-arn <jobRuntimeRole> \
        --job-driver '{
            "sparkSubmit": {
                "entryPoint": "s3://<YOUR BUCKET>/<PREFIX>/emrserverless-custom-images_2.12-1.0.jar",
                "entryPointArguments": ["40000000"],
                "sparkSubmitParameters": "--conf spark.executorEnv.JAVA_HOME=/usr/lib/jvm/java-11-openjdk-11.0.16.0.8-1.amzn2.0.1.x86_64 --conf spark.emr-serverless.driverEnv.JAVA_HOME=/usr/lib/jvm/java-11-openjdk-11.0.16.0.8-1.amzn2.0.1.x86_64 --class emrserverless.customjre.SyntheticAnalysis"
            }
        }' \
        --configuration-overrides '{
              "monitoringConfiguration": {
                "s3MonitoringConfiguration": {
                  "logUri": "s3://<YOUR BUCKET>/emrserverless/logs"
                }
              }
            }'

You can also extend this use case to install and use a custom Python version for your PySpark applications.

Use case 3: Monitor Spark metrics in a single Grafana dashboard

Spark JMX telemetry provides a lot of fine-grained details about every stage of the Spark application, even at the JVM level. These insights can be used to tune and optimize the Spark applications to reduce job runtime and cost. Prometheus is a popular tool used for collecting, querying, and visualizing application and host metrics of several different processes. After the metrics are collected in Prometheus, we can query these metrics or use Grafana to build dashboards and visualize them. In this use case, we use Amazon Managed Prometheus to gather Spark driver and executor metrics from our EMR Serverless Spark application, and we use Grafana to visualize the collected metrics. The following screenshot is an example Grafana dashboard for an EMR Serverless Spark application.

Prerequisites

Complete the following prerequisite steps:

  1. Create a VPC, private subnet, and security group. The private subnet should have a NAT gateway or VPC S3 endpoint attached. The security group should allow outbound access to the HTTPS port 443 and should have a self-referencing inbound rule for all traffic.


    Both the private subnet and security group should be associated with the two Amazon Managed Prometheus VPC endpoint interfaces.
  2. On the Amazon Virtual Private Cloud (Amazon VPC) console, create two endpoints for Amazon Managed Prometheus and the Amazon Managed Prometheus workspace. Associate the endpoints to the VPC, private subnet, and security group to both endpoints. Optionally, provide a name tag for your endpoints and leave everything else as default.

  3. Create a new workspace on the Amazon Managed Prometheus console.
  4. Note the ARN and the values for Endpoint – remote write URL and Endpoint – query URL.
  5. Attach the following policy to your Amazon EMR Serverless job runtime IAM role to provide remote write access to your Prometheus workspace. Replace the ARN copied from the previous step in the Resource section of "Sid": "AccessToPrometheus". This role should also have permissions to your S3 bucket where you will be storing your application JAR and logs.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "AccessToPrometheus",
                "Effect": "Allow",
                "Action": [
                    "aps:RemoteWrite"
                ],
                "Resource": "arn:aws:aps:<region>:<your AWS account>:workspace/<Workspace_ID>"
            }, {
                "Sid": "AccessToS3Buckets",
                "Effect": "Allow",
                "Action": [
                    "s3:PutObject",
                    "s3:GetObject",
                    "s3:ListBucket"
                ],
                "Resource": [
                    "arn:aws:s3:::<YOUR-BUCKET>",
                    "arn:aws:s3:::<YOUR-BUCKET>/*"
                ]
            }
        ]
    }

  6. Create an IAM user or role with permissions to create and query the Amazon Managed Prometheus workspace.

We use the same IAM user or role to authenticate in Grafana or query the Prometheus workspace.

Create an image to install the Prometheus agent

We create a custom image from the base EMR Serverless image to do the following:

  • Update the Spark metrics configuration to use PrometheusServlet to publish driver and executor JMX metrics in Prometheus format
  • Download and install the Prometheus agent
  • Upload the configuration YAML file to instruct the Prometheus agent to send the metrics to the Amazon Managed Prometheus workspace

Create the Prometheus config YAML file to scrape the driver, executor, and application metrics. You can run the following example commands on the EC2 instance.

  1. Copy the prometheus.yaml file from our S3 path:
    aws s3 cp s3://aws-bigdata-blog/artifacts/BDB-2771/prometheus-config/prometheus.yaml .

  2. Modify prometheus.yaml to replace the Region and value of the remote_write URL with the remote write URL obtained from the prerequisites:
    ## Replace your AMP workspace remote write URL 
    endpoint_url="https://aps-workspaces.<region>.amazonaws.com/workspaces/<ws-xxxxxxx-xxxx-xxxx-xxxx-xxxxxx>/api/v1/remote_write"
    
    ## Replace the remote write URL and region. Following is example for us-west-2 region. Modify the command for your region. 
    sed -i "s|region:.*|region: us-west-2|g" prometheus.yaml
    sed -i "s|url:.*|url: ${endpoint_url}|g" prometheus.yaml

  3. Upload the file to your own S3 bucket:
    aws s3 cp prometheus.yaml s3://<YOUR BUCKET>/<PREFIX>/

  4. Create the following Dockerfile inside a new directory named prometheus on the same EC2 instance that runs the Docker service. Provide the S3 path where you uploaded the prometheus.yaml file.
    # Pull base image
    FROM public.ecr.aws/emr-serverless/spark/emr-6.9.0:latest
    
    USER root
    
    # Install Prometheus agent
    RUN yum install -y wget && \
        wget https://github.com/prometheus/prometheus/releases/download/v2.26.0/prometheus-2.26.0.linux-amd64.tar.gz && \
        tar -xvf prometheus-2.26.0.linux-amd64.tar.gz && \
        rm -rf prometheus-2.26.0.linux-amd64.tar.gz && \
        cp prometheus-2.26.0.linux-amd64/prometheus /usr/local/bin/
    
    # Change Spark metrics configuration file to use PrometheusServlet
    RUN cp /etc/spark/conf.dist/metrics.properties.template /etc/spark/conf/metrics.properties && \
        echo -e '\
     *.sink.prometheusServlet.class=org.apache.spark.metrics.sink.PrometheusServlet\n\
     *.sink.prometheusServlet.path=/metrics/prometheus\n\
     master.sink.prometheusServlet.path=/metrics/master/prometheus\n\
     applications.sink.prometheusServlet.path=/metrics/applications/prometheus\n\
     ' >> /etc/spark/conf/metrics.properties
    
     # Copy the prometheus.yaml file locally. Change the value of bucket and prefix to where you stored your prometheus.yaml file
    RUN aws s3 cp s3://<YOUR BUCKET>/<PREFIX>/prometheus.yaml .
    
     # Create a script to start the prometheus agent in the background
    RUN echo -e '#!/bin/bash\n\
     nohup /usr/local/bin/prometheus --config.file=/home/hadoop/prometheus.yaml </dev/null >/dev/null 2>&1 &\n\
     echo "Started Prometheus agent"\n\
     ' >> /home/hadoop/start-prometheus-agent.sh && \ 
        chmod +x /home/hadoop/start-prometheus-agent.sh
    
     # EMRS will run the image as hadoop
    USER hadoop:hadoop

  5. Build the Dockerfile and push to Amazon ECR, providing your AWS account ID and Region:
    sudo docker build -t local/emr-serverless-ci-prometheus /home/ec2-user/prometheus/ --no-cache --pull
    sudo docker tag local/emr-serverless-ci-prometheus <your AWS account ID>.dkr.ecr.<region>.amazonaws.com/emr-serverless-ci-examples:emr-serverless-ci-prometheus
    sudo docker push <your AWS account ID>.dkr.ecr.<region>.amazonaws.com/emr-serverless-ci-examples:emr-serverless-ci-prometheus
    

Submit the Spark application

After the Docker image has been pushed successfully, you can create the serverless Spark application with the custom image you created. We use the AWS CLI to submit Spark jobs with the custom image on EMR Serverless. Your AWS CLI has to be upgraded to the latest version to run the following commands.

  1. In the following AWS CLI command, provide your AWS account ID and Region. Additionally, provide the subnet and security group from the prerequisites in the network configuration. In order to successfully push metrics from EMR Serverless to Amazon Managed Prometheus, make sure that you are using the same VPC, subnet, and security group you created based on the prerequisites.
    aws emr-serverless create-application \
    --name monitor-spark-with-ci \
    --region <region> \
    --release-label emr-6.9.0 \
    --type SPARK \
    --network-configuration subnetIds=<subnet-xxxxxxx>,securityGroupIds=<sg-xxxxxxx> \
    --image-configuration '{ "imageUri": "<your AWS account ID>.dkr.ecr.<region>.amazonaws.com/emr-serverless-ci-examples:emr-serverless-ci-prometheus" }'

  2. Copy the application JAR to your S3 bucket:
    aws s3 cp s3://aws-bigdata-blog/artifacts/BDB-2771/code/emrserverless-custom-images_2.12-1.0.jar s3://<YOUR BUCKET>/<PREFIX>/emrserverless-custom-images_2.12-1.0.jar

  3. In the following command, provide the name of the S3 bucket and prefix where you stored your application JAR. Additionally, provide the applicationId value obtained from the create-application command and your EMR Serverless job runtime IAM role ARN from the prerequisites, with permissions to write to the Amazon Managed Prometheus workspace.
    aws emr-serverless start-job-run \
        --region <region> \
        --application-id <applicationId> \
        --execution-role-arn <jobRuntimeRole> \
        --job-driver '{
            "sparkSubmit": {
                "entryPoint": "s3://<YOUR BUCKET>/<PREFIX>/emrserverless-custom-images_2.12-1.0.jar",
                "entryPointArguments": ["40000000"],
                "sparkSubmitParameters": "--conf spark.ui.prometheus.enabled=true --conf spark.executor.processTreeMetrics.enabled=true --class emrserverless.prometheus.SyntheticAnalysis"
            }
        }' \
        --configuration-overrides '{
              "monitoringConfiguration": {
                "s3MonitoringConfiguration": {
                  "logUri": "s3://<YOUR BUCKET>/emrserverless/logs"
                }
              }
            }'
    

Inside this Spark application, we run the bash script in the image to start the Prometheus process. You will need to add the following lines to your Spark code after initiating the Spark session if you’re planning to use this image to monitor your own Spark application:

import scala.sys.process._
Seq("/home/hadoop/start-prometheus-agent.sh").!!

For PySpark applications, you can use the following code:

import os
os.system("/home/hadoop/start-prometheus-agent.sh")

Query Prometheus metrics and visualize in Grafana

About a minute after the job changes to Running status, you can query Prometheus metrics using awscurl.

  1. Replace the value of AMP_QUERY_ENDPOINT with the query URL you noted earlier, and provide the job run ID obtained after submitting the Spark job. Make sure that you’re using the credentials of an IAM user or role that has permissions to query the Prometheus workspace before running the commands.
    $ export AMP_QUERY_ENDPOINT="https://aps-workspaces.<region>.amazonaws.com/workspaces/<Workspace_ID>/api/v1/query"
    $ awscurl -X POST --region <region> \
                              --service aps "$AMP_QUERY_ENDPOINT?query=metrics_<jobRunId>_driver_ExecutorMetrics_TotalGCTime_Value{}"
    

    The following is example output from the query:

    {
        "status": "success",
        "data": {
            "resultType": "vector",
            "result": [{
                "metric": {
                    "__name__": "metrics_00f6bueadgb0lp09_driver_ExecutorMetrics_TotalGCTime_Value",
                    "instance": "localhost:4040",
                    "instance_type": "driver",
                    "job": "spark-driver",
                    "spark_cluster": "emrserverless",
                    "type": "gauges"
                },
                "value": [1671166922, "271"]
            }]
        }
    }

  2. Install Grafana on your local desktop and configure our AMP workspace as a data source.Grafana is a commonly used platform for visualizing Prometheus metrics.
  3. Before we start the Grafana server, enable AWS SIGv4 authentication in order to sign queries to AMP with IAM permissions.
    ## Enable SIGv4 auth 
    export AWS_SDK_LOAD_CONFIG=true 
    export GF_AUTH_SIGV4_AUTH_ENABLED=true

  4. In the same session, start the Grafana server. Note that the Grafana installation path may vary based on your OS configurations. Modify the command to start the Grafana server in case your installation path is different from /usr/local/. Also, make sure that you’re using the credentials of an IAM user or role that has permissions to query the Prometheus workspace before running the following commands
    ## Start Grafana server
    grafana-server --config=/usr/local/etc/grafana/grafana.ini \
      --homepath /usr/local/share/grafana \
      cfg:default.paths.logs=/usr/local/var/log/grafana \
      cfg:default.paths.data=/usr/local/var/lib/grafana \
      cfg:default.paths.plugins=/usr/local/var/lib/grafana/plugin

  5. Log in to Grafana and go on the data sources configuration page /datasources to add your AMP workspace as a data source.The URL should be without the /api/v1/query at the end. Enable SigV4 auth, then choose the appropriate Region and save.

When you explore the saved data source, you can see the metrics from the application we just submitted.

You can now visualize these metrics and create elaborate dashboards in Grafana.

Clean up

When you’re done running the examples, clean up the resources. You can use the following script to delete resources created in EMR Serverless, Amazon Managed Prometheus, and Amazon ECR. Pass the Region and optionally the Amazon Managed Prometheus workspace ID as arguments to the script. Note that this script will not remove EMR Serverless applications in Running status.

aws s3 cp s3://aws-bigdata-blog/artifacts/BDB-2771/cleanup/cleanup_resources.sh .
chmod +x cleanup_resources.sh
sh cleanup_resources.sh <region> <AMP Workspace ID> 

Conclusion

In this post, you learned how to use custom images with Amazon EMR Serverless to address some common use cases. For more information on how to build custom images or view sample Dockerfiles, see Customizing the EMR Serverless image and Custom Image Samples.


About the Author

Veena Vasudevan is a Senior Partner Solutions Architect and an Amazon EMR specialist at AWS focusing on Big Data and Analytics. She helps customers and partners build highly optimized, scalable, and secure solutions; modernize their architectures; and migrate their Big Data workloads to AWS.
Running Next.js applications with serverless services on AWS

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/running-next-js-applications-with-serverless-services-on-aws/

This is written by Julian Bonilla, Senior Solutions Architect, and Matthew de Anda, Startup Solutions Architect.

React is a popular JavaScript library used to create single-page applications (SPAs). React focuses on helping to build UIs, but leaves it up to developers to decide how to accomplish other aspects involved with developing a SPA.

Next.js is a React framework to help provide more structure and solve common application requirements such as routing and data fetching. Next.js also provides multiple types of rendering methods – Static Site Generation (SSG), Server-Side Rendering (SSR), Incremental Static Regeneration (ISR), and Client-Side Rendering (CSR).

This post demonstrates how to build a Next.js application with Serverless services on AWS and explains Next.js Server-Side rendering. To deploy this solution and to provision the AWS resources, you can use either AWS Serverless Application Model (AWS SAM) or AWS Cloud Development Kit (CDK). Both are open-source frameworks to automate AWS deployment. AWS SAM is a declarative framework for building serverless applications and CDK is an imperative framework to define cloud application resources using familiar programming languages.

Overview

To render a Next.js application, you use Amazon S3, Amazon CloudFront, Amazon API Gateway, and AWS Lambda. Static resources are hosted in a private S3 bucket with a CloudFront distribution. Since static sources are generated at build time, this takes advantage of CloudFront so browsers can load these files cached on the network edge instead of from the server.

The Next.js application components that uses server-side rendering is rendered with a Lambda function using AWS Lambda Web Adapter. The CloudFront distribution is configured to forward requests to the API Gateway endpoint, which then calls the Lambda function.

  1. Static files (for example, CSS, JavaScript, and HTML) are mapped to /_next/static/* and /public/*.
  2. Server-side rendering is mapped with default behavior (*).
  3. The AWS Lambda Adapter runs Next.js Output File Tracing.

What’s Next.js?

Next.js is a React framework that creates a more opinionated approach to building web applications while providing additional structure and features such as Server-Side Rendering and Static Site Generation.

These additional rendering options provide more flexibility over the typical ways a React application is built, which is to render in the client’s browser with JavaScript. This can help in scenarios where customers have JavaScript disabled and can improve search engine optimization (SEO). While you can implement SSR in React applications, Next.js makes it simpler for developers.

Next.js rendering strategies

These are the different rendering strategies offered by Next.js:

  • Static Site Generation generates static resources at build time and is a good rendering strategy for static content that rarely changes and SEO.
  • Server-Side Rendering generates each page on-demand at request time and is good for pages that are dynamic. Since from the browser perspective it’s still pre-rendered, like Static Site Generation, it’s also good for SEO.
  •  Incremental Static Regeneration is a new rendering strategy that is good for apps with many pages where build times are high. With Incremental Static Regeneration, you can build page per-page without needing to rebuild the entire app.
  • Client-Side Rendering is the typical rendering strategy where the application is rendered in the browser with JavaScript. Next.js lets you choose the appropriate rendering method page-by-page. When a Next.js application is built, Next.js transforms the application to production-optimized files. You have HTML for statically generated pages, JavaScript for rendering on the server, JavaScript for rendering on the client, and CSS files.

Next.js also supports static HTML export, which has no server side component. Features that require a server are not supported with this approach. These apps can be hosted from S3 and CloudFront.

The remainder of this post focuses on Static Site Generation and Server-Side Rendering.

Next.js application project structure

Understanding how Next.js structures projects can give insight into how you deploy the application. A page is a React Component exported from files in the “pages” directory. These files are also used for routing where pages/index.js is routed to / route.

By default, these pages are pre-rendered. Static assets, such as images, are stored under “public” directory and can be referenced from /. Since these files are best stored in persistent storage and backed by a content delivery network (CDN), you can add a prefix in the implementation to distinguish these static files.

To create dynamic routes, add brackets to a page file – for example, pages/user/[id].js. This creates a statically generated page with the path /user/<id> where <id> can be dynamic.

API routes provide a way to create an API endpoint and are located in the pages/api directory. When building, Next.js generates an optimized version of your application under the .next directory. Static files not stored in the public directory are in .next/static. These static files are expected to be uploaded as _next/static to a CDN.

No other code in the .next/directory should be uploaded to a CDN because that would expose server code and other configuration.

Implementation

Next.js pre-renders HTML for every page using Static Site Generation or Server-side Rendering. For Static Site Generation, pages are rendered at build time and can be cached in CloudFront. Server-side rendered pages are rendered at request time, and typically fetch data from downstream resources on each request.

Clients connect to a CloudFront distribution, which is configured to forward requests for static resources to S3 and all other requests to API Gateway. API Gateway forwards requests to the Next.js application running on Lambda, which performs the server-side rendering.

At build time, Next.js Output File Tracing determines the minimal set of files needed for deploying to Lambda. The files are automatically copied to a standalone directory and must be enabled in next.config.js.

const nextConfig = {
  reactStrictMode: true,
  output: 'standalone',
}
module.exports = nextConfig

Since the Next.js application is essentially a webserver, this example uses the AWS Lambda Web Adapter as a Lambda layer to convert incoming events from API Gateway to HTTP requests that Next.js can process.

Once processed, the AWS Lambda Web Adapter converts the HTTP response back to a Lambda event response. The Lambda handler is configured to run the minimal server.js file created by the standalone build step.

The CloudFront distribution has two origins: one for the S3 bucket and another for the API Gateway. Two behaviors are created to specify path patterns to route static content produced by Next.js and static resources stored under the public/static directory. Next.js uses the public directory under root to serve static assets such as images.

These assets are then served under / so if you add public/me.png, it would be served at /me.png. This makes it harder to create a CloudFront behavior for these assets. One workaround is to create a static directory under the public directory and then map it to the CloudFront behavior. The default(*) path pattern behavior has the origin set to API Gateway with caching disabled.

Prerequisites and deployment

Refer to the project in its GitHub repository for instructions to deploy the solution using AWS SAM or AWS CDK. Multiple resources are provisioned for you as part of the deployment, and it takes several minutes to complete. The example Next.js application deployed is created using Create Next App.

Understanding the Next.js Application

To create a new page, you create a file under the pages directory and that creates a route based on the name (e.g. pages/hello.js creates route /hello). To create dynamic routes, create a file following the project’s example of pages/posts/[id].js to produce routes for posts/1, posts/2, and so forth.

For API routes, any file added to the directory pages/api is mapped to /api/* and becomes an API endpoint. These are server-side only bundles hosted by API Gateway and Lambda.

Conclusion

This blog shows how to run Next.js applications using S3, CloudFront, API Gateway, and Lambda. This architecture supports building Next.js applications that can use static-site generation, server-side rendering, and client-side rendering. The blog also covers how you can use open-source frameworks, AWS SAM and CDK, to build and deploy your Next.js applications.

If your organization is looking for a fully managed hosting of your Next.js applications, AWS Amplify Hosting supports Next.js. If interested in learning more about server-side rendering and micro-frontends, see Server-side rendering micro-frontends – the architecture.

For more serverless learning resources, visit Serverless Land.

Serverless ICYMI Q4 2022

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/compute/serverless-icymi-q4-2022/

Welcome to the 20th edition of the AWS Serverless ICYMI (in case you missed it) quarterly recap. Every quarter, we share all the most recent product launches, feature enhancements, blog posts, webinars, Twitch live streams, and other interesting things that you might have missed!In case you missed our last ICYMI, check out what happened last quarter here.

AWS Lambda

For developers using Java, AWS Lambda has introduced Lambda SnapStart. SnapStart is a new capability that can improve the start-up performance of functions using Corretto (java11) runtime by up to 10 times, at no extra cost.

To use this capability, you must enable it in your function and then publish a new version. This triggers the optimization process. This process initializes the function, takes an immutable, encrypted snapshot of the memory and disk state, and caches it for reuse. When the function is invoked, the state is retrieved from the cache in chunks, on an as-needed basis, and it is used to populate the execution environment.

The ICYMI: Serverless pre:Invent 2022 post shares some of the launches for Lambda before November 21, like the support of Lambda functions using Node.js 18 as a runtime, the Lambda Telemetry API, and new .NET tooling to support .NET 7 applications.

Also, now Amazon Inspector supports Lambda functions. You can enable Amazon Inspector to scan your functions continually for known vulnerabilities. The log4j vulnerability shows how important it is to scan your code for vulnerabilities continuously, not only after deployment. Vulnerabilities can be discovered at any time, and with Amazon Inspector, your functions and layers are rescanned whenever a new vulnerability is published.

AWS Step Functions

There were many new launches for AWS Step Functions, like intrinsic functions, cross-account access capabilities, and the new executions experience for Express Workflows covered in the pre:Invent post.

During AWS re:Invent this year, we announced Step Functions Distributed Map. If you need to process many files, or items inside CSV or JSON files, this new flow can help you. The new distributed map flow orchestrates large-scale parallel workloads.

This feature is optimized for files stored in Amazon S3. You can either process in parallel multiple files stored in a bucket, or process one large JSON or CSV file, in which each line contains an independent item. For example, you can convert a video file into multiple .gif animations using a distributed map, or process over 37 GB of aggregated weather data to find the highest temperature of the day. 

Amazon EventBridge

Amazon EventBridge launched two major features: Scheduler and Pipes. Amazon EventBridge Scheduler allows you to create, run, and manage scheduled tasks at scale. You can schedule one-time or recurring tasks across 270 services and over 6.000 APIs.

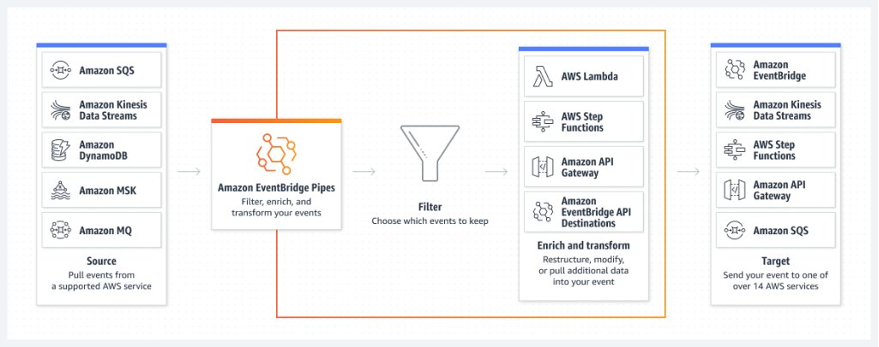
Amazon EventBridge Pipes allows you to create point-to-point integrations between event producers and consumers. With Pipes you can now connect different sources, like Amazon Kinesis Data Streams, Amazon DynamoDB Streams, Amazon SQS, Amazon Managed Streaming for Apache Kafka, and Amazon MQ to over 14 targets, such as Step Functions, Kinesis Data Streams, Lambda, and others. It not only allows you to connect these different event producers to consumers, but also provides filtering and enriching capabilities for events.

EventBridge now supports enhanced filtering capabilities including:

  • Matching against characters at the end of a value (suffix filtering)
  • Ignoring case sensitivity (equals-ignore-case)
  • OR matching: A single rule can match if any conditions across multiple separate fields are true.

It’s now also simpler to build rules, and you can generate AWS CloudFormation from the console pages and generate event patterns from a schema.

AWS Serverless Application Model (AWS SAM)

There were many announcements for AWS SAM during this quarter summarized in the ICMYI: Serverless pre:Invent 2022 post, like AWS SAM Connectors, SAM CLI Pipelines now support OpenID Connect Protocol, and AWS SAM CLI Terraform support.

AWS Application Composer

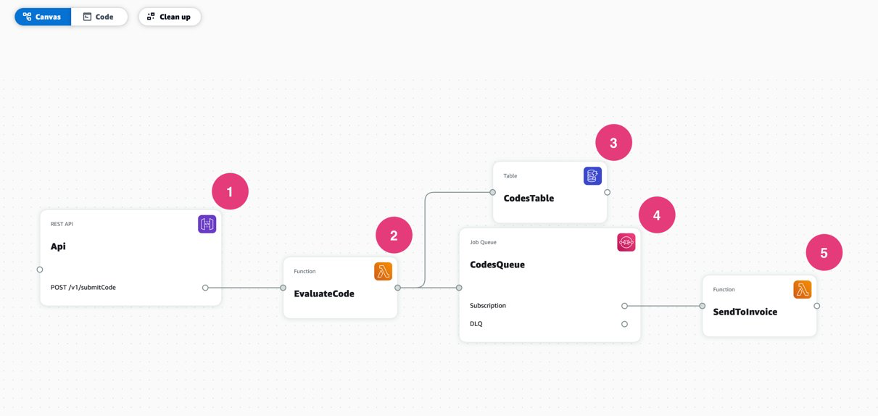
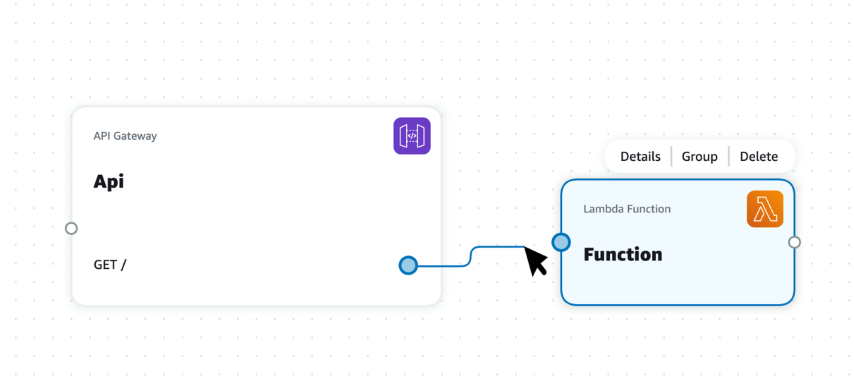
AWS Application Composer is a new visual designer that you can use to build serverless applications using multiple AWS services. This is ideal if you want to build a prototype, review with others architectures, generate diagrams for your projects, or onboard new team members to a project.

Within a simple user interface, you can drag and drop the different AWS resources and configure them visually. You can use AWS Application Composer together with AWS SAM Accelerate to build and test your applications in the AWS Cloud.

AWS Serverless digital learning badges

The new AWS Serverless digital learning badges let you show your AWS Serverless knowledge and skills. This is a verifiable digital badge that is aligned with the AWS Serverless Learning Plan.

This badge proves your knowledge and skills for Lambda, Amazon API Gateway, and designing serverless applications. To earn this badge, you must score at least 80 percent on the assessment associated with the Learning Plan. Visit this link if you are ready to get started learning or just jump directly to the assessment. 

News from other services:

Amazon SNS

Amazon SQS

AWS AppSync and AWS Amplify

Observability

AWS re:Invent 2022

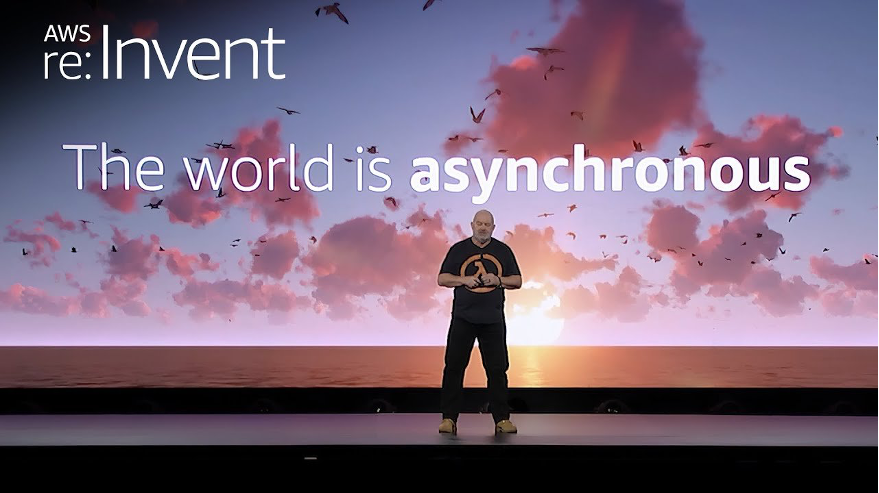
AWS re:Invent was held in Las Vegas from November 28 to December 2, 2022. Werner Vogels, Amazon’s CTO, highlighted event-driven applications during his keynote. He stated that the world is asynchronous and showed how strange a synchronous world would be. During the keynote, he showcased Serverlesspresso as an example of an event-driven application. The Serverless DA team presented many breakouts, workshops, and chalk talks. Rewatch all our breakout content:

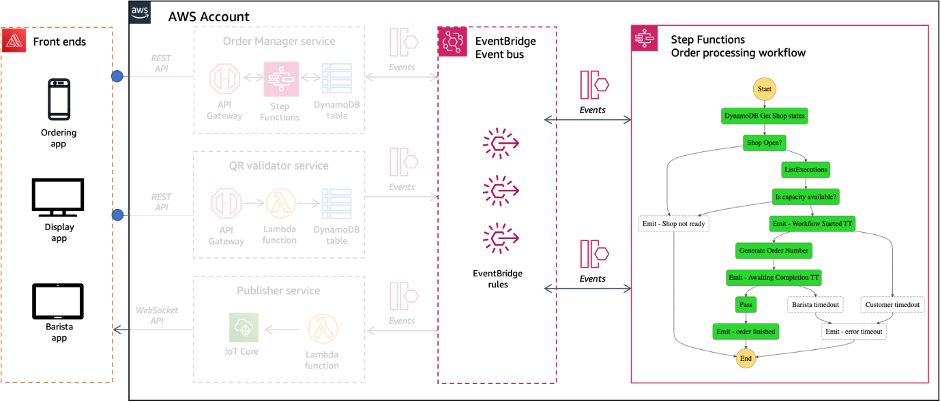
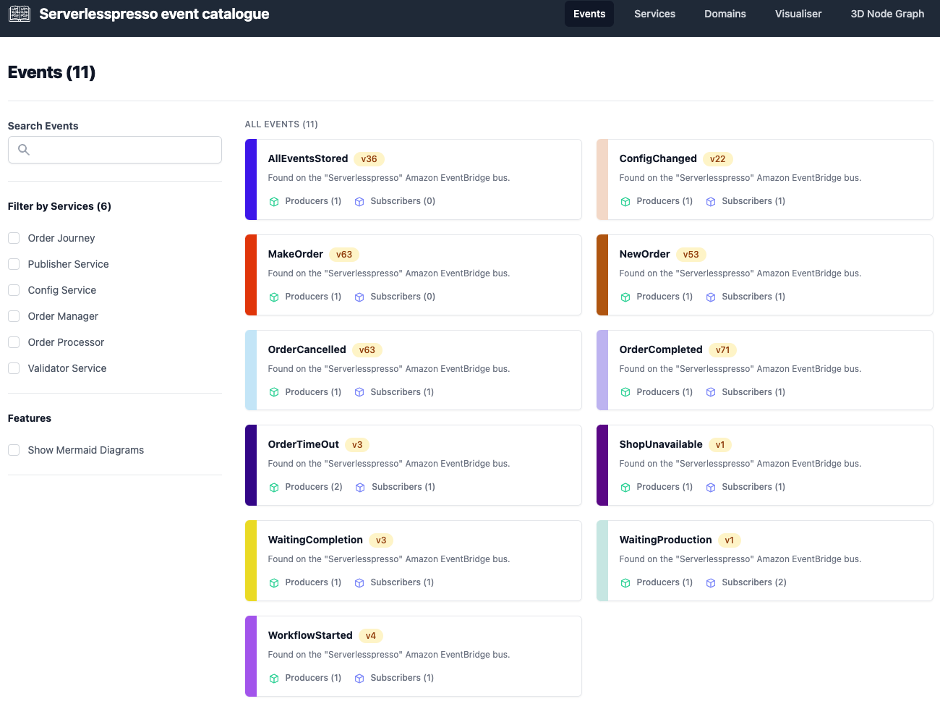
In addition, we brought Serverlesspresso back to Vegas. Serverlesspresso is a contactless, serverless order management system for a physical coffee bar. The architecture comprises several serverless apps that support an ordering process from a customer’s smartphone to a real espresso bar. The customer can check the virtual line, place an order, and receive a notification when their drink is ready for pickup.

Serverless blog posts

October

November

December

Videos

Serverless Office Hours – Tuesday 10 AM PT

Weekly live virtual office hours: In each session, we talk about a specific topic or technology related to serverless and open it up to helping with your real serverless challenges and issues. Ask us anything about serverless technologies and applications.

YouTube: youtube.com/serverlessland

Twitch: twitch.tv/aws

October

November

December

FooBar Serverless YouTube Channel

Marcia Villalba frequently publishes new videos on her popular FooBar Serverless YouTube channel.

October

November

December

Still looking for more?

The Serverless landing page has more information. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials. If you want to learn more about event-driven architectures, read our new guide that will help you get started.

You can also follow the Serverless Developer Advocacy team on Twitter and LinkedIn to see the latest news, follow conversations, and interact with the team.

For more serverless learning resources, visit Serverless Land.

Top 10 AWS Architecture Blog posts of 2022

Post Syndicated from Elise Chahine original https://aws.amazon.com/blogs/architecture/top-10-aws-architecture-blog-posts-of-2022/

As we wrap up 2022, we want to take a moment to shine a bright light on our readers, who spend their time exploring our posts, providing generous feedback, and asking poignant questions! Much appreciation goes to our Solutions Architects, who work tirelessly to identify and produce what our customers need.

Without any further ado, here are the top 10 AWS Architecture Blog posts of 2022…

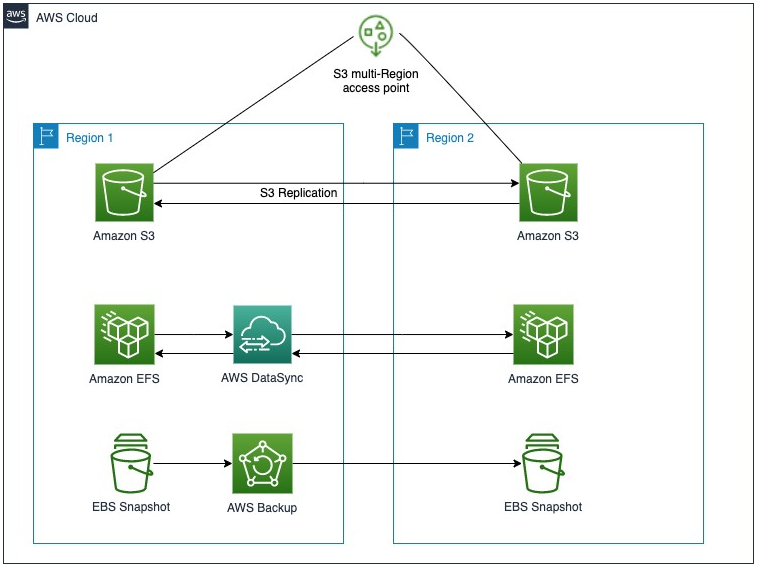
#1: Creating a Multi-Region Application with AWS Services – Part 2, Data and Replication

Joe Chapman, Senior Solutions Architect, and Seth Eliot, Principal Developer Advocate, come in at #1 with a review of AWS services that offer cross-Region data replication—getting data where in needs to be, quickly!

#1 2022

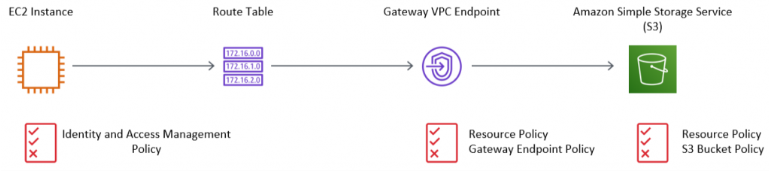
#2: Reduce Cost and Increase Security with Amazon VPC Endpoints

Nigel Harris and team. explain the benefits of using Amazon VPC endpoints, and how to appropriately restrict access to endpoints and the services they connect to. Learn more by taking the VPC Endpoint Workshop in the AWS Workshop Studio!

#2 2022

#3: Multi-Region Migration using AWS Application Migration Service

In this technical how-to post, Shreya Pathak and Medha Shree demonstrate how to configure AWS Application Migration Service to migrate workloads from one AWS Region to another.

#4: Let’s Architect! Architecting for Sustainability

The Let’s Architect! Team claims 4 of the top 10 spots for 2022! Luca, Laura, Vittorio, and Zamira kick-off the series by providing material to help our customers design sustainable architectures and create awareness on the topic of sustainability.

#5: Let’s Architect! Serverless architecture on AWS

In this post, the Let’s Architect! Team shares insights into reimagining a serverless environment, including how to start prototype and scale to mass adoption using decoupled systems, integration approaches, serverless architectural patterns and best practices, and more!

#6: Let’s Architect! Tools for Cloud Architects

For a three-in-a-row, the Let’s Architect! Team shares tools and methodologies for architects to learn and experiment with. This post was also a celebration of International Women’s Day, with half of the tools detailed developed with or by women!

#7: Announcing updates to the AWS Well-Architected Framework

Well-Architected is tried and true AWS, describing key concepts, design principles, and architecture best practices for cloud workloads. In this post, Haleh Najafzadeh, Senior Solutions Architecture Manager for AWS Well-Architected, updates our readers on improvements to the Well-Architected Framework across all six pillars.

#8: Creating a Multi-Region Application with AWS Services – Part 3, Application Management and Monitoring

Joe and Seth are back at #8, covering AWS services and features used for messaging, deployment, monitoring, and management in multi-Region applications.

#9: Let’s Architect! Creating resilient architecture

“The need for resilient workloads transcends all customer industries…” In their last top 10 post, the team provides resources to help build resilience into your AWS architecture.

#10: Using DevOps Automation to Deploy Lambda APIs across Accounts and Environments

Subrahmanyam Madduru and team demonstrate how to automate release deployments in a repeatable and agile manner, reducing manual errors and increasing the speed of delivery for business capabilities.

Goodbye, 2022!

A big thank you to all our readers and authors! Your feedback and collaboration are appreciated and help us produce better content every day.

From all of us at the AWS Architecture Blog, happy holidays!

A modern approach to implementing the serverless Customer Data Platform

Post Syndicated from Larry Bell original https://aws.amazon.com/blogs/architecture/a-modern-approach-to-implementing-the-serverless-customer-data-platform-cdp/

When building a Customer Data Platform (CDP), advertising and marketing Independent Software Vendors (ISVs) face a unique set of challenges. The ISV can help organizations with the heavy lifting required to build, secure, and maintain near real-time, high volume CDPs. However, architecting CDPs using traditional on-premises technologies can introduce multiple complexities and can limit deployment options. One strategy that may address these complexities is to use serverless technologies.

Serverless technologies feature automatic scaling, built-in high availability, and a pay-for-use billing model to increase agility, optimize costs, and reduce infrastructure management tasks such as capacity provisioning and patching. Using tools such as CloudFormation, each layer of the serverless CDP can be deployed on-demand in an independent manner to maximize portability and optimize performance.

A Software as a Service (SaaS) CDP usually has significantly more data in a multi-tenant environment than a single instance of a CDP. Clients of a SaaS solution need to continually expand across different channels, and often across many AWS Regions. In some cases, an ISV might have an existing infrastructure that was built before some of these modern capabilities and techniques were mature. Today, an ISV can build or even modernize an existing CDP and gain huge benefits from a serverless implementation.

This blog post explores how to use serverless technologies for the CDP. A modern, serverless CDP architecture can enable the ISV and the client companies to deliver in weeks instead of months, and provide a resilient infrastructure that supports agility and global deployment while maximizing operational efficiency and optimizing cost. This frees up technical resources to focus on differentiated product development instead of managing servers.

Serverless implementation of a CDP on AWS

A serverless architecture uses AWS services that don’t require the configuration of a server to provide an implementation. Serverless technology allows you to focus more time on rapidly building different components of the marketing CDP. The benefits of a CDP include the collection, aggregation, and organization of customer data sources. Implementing the CDP using serverless technology reduces the need to focus on managing infrastructure while reducing time to market, increasing agility, and resulting in cost optimization. Figure 1 is an architecture diagram that describes how various data sources can be prepared for consumption in the component based Customer Data Platform.

Marketing CDP reference on AWS

Figure 1. Marketing CDP reference on AWS

  1. Source systems of customer data include customer interactions, clickstreams and call center logs.
  2. Data from customer touchpoints is ingested into the marketing customer data platform (CDP) data lake using Amazon Kinesis, Amazon AppFlow, Amazon EKS and an Amazon API Gateway.
  3. Ingested data is sent – in its original, immutable format – to an Amazon Simple Storage Service (Amazon S3) Raw Zone bucket
  4. Raw data is then transformed into efficient data formats – such as Parquet or Avro – and moved to a Clean Zone Amazon S3 bucket.
  5. CDP processing and pipeline orchestration is conducted using purpose-built data processing components and transformation libraries through AWS Step Functions and then Amazon Personalize, AWS Lambda, and AWS Glue.
  6. Data in the Amazon S3 Curated Zone is now ready for post-CDP-processing consumption and is organized by subject areas, segments, and profiles.
  7. The analytics layer uses Amazon Redshift, Amazon QuickSight, Amazon SageMaker and Amazon Athena to natively integrate with the Curated Zone for analytics, dashboards, ad hoc reporting, and ML purposes.
  8. Customer data is then aggregated across platforms and published using customer APIs for consumption using Amazon DynamoDB and an Amazon API Gateway.
  9. Amazon Pinpoint and Amazon Connect are used to activate multiple customer channels such as mobile push, voice, and email for targeted marketing communications.
  10. Using AWS Lake Formation, fine-grained access controls can be enforced on catalog tables, columns, and rows on the data lake.
  11. The resulting catalog in AWS Glue helps you manage both business and technical metadata, with versioning, at scale.

Serverless implementation for ingestion

There are several methods of ingesting customer data, both internal to a customer and from external sources. Serverless options for ingestion could provide benefits to an ISV like cost or agility but it depends upon the use case. Examining serverless options for ingestion should be part of any modernization effort. If the CDP needs to stream data sources and ingest that data in near-real time, the ISV can use Amazon Kinesis. If you want a more traditional extract, transform, and load (ETL) tool, AWS Glue offers a serverless option to generate code that can be customized. AWS Glue DataBrew offers a visual data preparation tool. For more advanced governance and control, you can use AWS Lake Formation. To ingest sources using an API, the Amazon API Gateway provides a serverless approach. If you need more control over the ingestion, the use of customized scripts in Amazon AppFlow or Amazon Managed Streaming for Apache Kafka (Amazon MSK) can provide a solution.

Serverless storage implementation

Amazon Simple Storage Service (Amazon S3) provides a serverless, cost-effective solution for virtually unbounded amounts of storage and read-write bandwidth. As per the reference architecture, there are three purpose-specific zones:

  • A raw zone containing the original, immutable version of data
  • A trusted zone which can be used as a working area to combine, enhance and clean the data
  • A refined zone containing data ready for consumption by users and applications

This structure allows the improvement of customer data and profiles, and provides the ability to integrate various data sources and a structure that allows customer data to be recreated in a manner consistent with changing business rules.

Serverless cataloging implementation

The cataloging services provide a grouping of the elements contained in structured and unstructured data sources that is intuitive and easy to understand, similar to a single relational database. AWS Glue Data Catalog gives logical structure to the data lake by allowing users to define tables and columns on top of Amazon S3 data sets. This serverless solution integrates with other analytics tools to enable data discovery and consistent usage. Fine-grained governance and access can also be enforced by AWS Lake Formation.

Serverless processing

There are great choices for implementing processing, using serverless technologies. A CDP platform can package code and run on demand without servers using AWS Lambda or AWS Step Functions depending up the complexity of the processing pipeline. These services can enable complex processing on customer data and profiles. Amazon SageMaker is a great serverless choice for incorporating artificial Intelligence / machine learning into your processing stream. For processing using big data techniques Amazon EMR Serverless is a good serverless option.

Serverless implementation for consumption

Analytics for the CDP provides several serverless technologies that enable different types of insights. For interactive SQL queries that integrate with our serverless AWS Glue Catalog, there is Amazon Athena. Athena provides SQL access to various data source, and can also use federated query functionality to connect to third-party sources, even if that data is sitting on another cloud or in a vendor’s environment. Athena can also work as an interface (middleware) to other reporting solutions.

If performance is a concern, Amazon Redshift is fast, petabyte-scale data warehouse solution that has a serverless option and fully integrates with these solutions. For a data visualization tool that can be embedded in your application or work as a standalone portal, examine Amazon QuickSight.

To enable collaboration, many use cases can use Amazon API Gateway to securely publish and expose API endpoints for consuming applications. This allows data to be shared from a single source of truth to consumers that use customer data for their processes. Most customers want to activate their customer data through marketing or advertising campaigns. To activate marketing communication over voice, email, text, or in-app messaging, you can use a serverless service called Amazon Pinpoint. For an omnichannel contact center support, we recommend Amazon Connect, which uses AI/ML and the CDP data to analyze customer sentiment, implement chatbots, and authenticate voice callers.

Serverless implementation for governance

AWS Lake Formation simplifies the process of configuring and securing access to the CDP. It can help orchestrate processing and ingestion, as well as enforcing fine-grained access controls on data catalogs. Other services such as AWS Glue DataBrew or Amazon Macie can identify and help mitigate exposure of Personally identifiable information (PII). AWS Config enables you to assess, audit, and evaluate the configurations of your AWS resources to automate the evaluation of recorded configurations against desired configurations.

Conclusion

This post described just some of the serverless solutions that are managed by AWS that allow you to build a modern, low-cost, data lake-centric CDP architecture in an accelerated manner. A decoupled, component-driven architecture lets you start small and quickly add new services to each independent component of the CDP. Use the Data Analytics Lens for guidance on designing, deploying, and architecting your analytics solution workloads in the AWS Cloud. Using this framework, you will learn the architectural best practices for designing and operating reliable, secure, efficient, and cost-effective systems in the cloud. Follow the links in this article to learn more about the services available in AWS that can help you build a serverless CDP.

Further reading

Amazon EMR Serverless cost estimator

Post Syndicated from Radhika Ravirala original https://aws.amazon.com/blogs/big-data/amazon-emr-serverless-cost-estimator/

Amazon EMR Serverless is a serverless option in Amazon EMR that makes it easy for data analysts and engineers to run applications using open-source big data analytics frameworks such as Apache Spark and Hive without configuring, managing, and scaling clusters or servers. You get all the features of the latest open-source frameworks with the performance-optimized runtime of Amazon EMR, and without having to plan and operate instances and clusters.

With Amazon EMR, you can run your analytics applications on dedicated EMR clusters, on existing Amazon Elastic Kubernetes Service (Amazon EKS) clusters, or using the new EMR Serverless deployment option where you don’t have to manage clusters or instances. When you build a Spark or Hive application using an Amazon EMR release, say Amazon EMR 6.8, you can run the application on EMR clusters, on EKS clusters using Amazon EMR on EKS, or using EMR Serverless without having to change the application.

To learn about the benefits of each deployment option in EMR Serverless, refer to What are some of the feature differences between EMR Serverless and Amazon EMR on EC2? in the Amazon EMR FAQ. You can also learn about the pricing for these options from the Amazon EMR pricing page. Many customers already run data analytics applications on EMR clusters, and find that the new serverless option is simpler and less expensive.

In this post, we discuss how you can estimate what it may cost to run an application that currently runs on EMR clusters using the new serverless option, and perform this analysis simply by using your current application metrics. This approach helps you evaluate and adopt the deployment option that is most cost effective for the application. However, the Amazon EMR pricing page doesn’t tell you how you can easily estimate the cost of running your existing EMR cluster applications on EMR Serverless. In the following sections, we describe an approach that enables you to do that.

Although the example in this post discusses how you can get a cost estimate for applications running on EMR clusters, you can also use the approach if you’re running a Spark or Hive application elsewhere, and want to estimate the cost of running it on EMR Serverless. For example, if you run self-managed Spark or Hive applications on Amazon Elastic Compute Cloud (Amazon EC2) clusters, or if you run Spark jobs on AWS Glue, we show you how you can use this approach to estimate the cost of running the application on EMR Serverless.

Estimating the cost of running applications on your EMR cluster

When you run applications on Amazon EMR clusters, you’re separately charged for the following:

  1. The Amazon EC2 price of running cluster instances (the price for the underlying servers)
  2. The price for Amazon Elastic Block Store (Amazon EBS) volumes, if you choose to attach EBS volumes
  3. The Amazon EMR price for the cluster instances

The total cost of running the cluster includes all three. There are a variety of Amazon EC2 pricing options you can choose from, including On Demand, 1-year and 3-year Reserved Instances, Capacity Savings Plans, and Spot Instances. The Amazon EC2 pricing option that you choose determines (a), the Amazon EC2 price. The cost of running the application on EMR clusters is the sum of (a), (b), and (c). You can compute this cost for the lifetime of running the cluster (from the time a cluster is started to the time the cluster is terminated), or for a specific period of time while the cluster is running. We recommend running the former, that is to compute (a), (b), and (c) from the time the cluster is started to the time the cluster is terminated. If you have set up tags for your Amazon EMR cluster, you can easily get the detailed cost report for your EMR cluster using AWS Cost Explorer.

Estimating the cost of running the same applications using EMR Serverless

When you run the same applications using EMR Serverless, you pay for the amount of vCPU, memory, and storage resources consumed by your applications. There is no separate charge for EC2 instances or EBS volumes. And, you only pay for the resources that are actually used by the application and not for EC2 instances provisioned. For example, when running applications on EMR clusters, when an EC2 instance in the cluster is partially utilized (say, 16 GB memory is used out of 64 GB available on the instance, or 4 VCPUs are utilized out of 16 VCPUs available on the instance), or when the EC2 instance is idle (for example, when the instance is initializing or waiting for an application to start), you still incur Amazon EC2, Amazon EMR, and Amazon EBS charges for the full EC2 instance and for the duration that the instance is active in the EMR cluster. With EMR Serverless, you only pay for the vCPU, memory, and storage resources used from the time workers start to run your Spark or Hive job until the time they stop.

To estimate the cost of running your EMR Spark or Hive application on EMR Serverless, you need to first aggregate the total compute vCore-seconds, memory MB-seconds, and storage GB-seconds consumed by each YARN application that ran on your EMR cluster, from the time the YARN container is started to the time the YARN container is terminated. You can obtain these metrics from YARN resource manager logs accessible from YARN timeline server or YARN CLI tools. You can retrieve the running time, vCore-seconds, and memory MB-seconds used by each of the YARN applications.

If your cluster only runs Spark applications, there is a simpler approach to estimate. Instead of obtaining the vCore-seconds, memory MB-seconds, and storage GB-seconds from YARN resource manager logs, you can obtain these metrics from Spark event logs. We have provided the tool EMR Servless Estimator, which can parse the Spark event logs for your applications and provide the aggregated metrics for your cost estimate.

After you get the usage metrics for your application, you can compute the estimated EMR Serverless cost using EMR Serverless pricing. Simply multiple your aggregated vCore-seconds with EMR Serverless vCPU pricing per second, multiply aggregated memory MB-seconds with the EMR Serverless memory pricing per second, and multiply storage GB-seconds with the EMR Serverless storage pricing per second (only if the storage requirements exceed 20 GB per worker). By adding up these costs for vCPU, memory, and storage, you can compare the cost of running the same applications on EMR Serverless.

In this approach, we assume that the performance of the application is equivalent. In other words, the size (vCPU, memory) and runtime duration for each YARN container on the EMR cluster is the same as the number, size, and runtime duration of workers needed to run the application on EMR Serverless. We make this assumption because the EMR runtime for an EMR release is the same regardless of whether the application is run on an EMR cluster or on EMR Serverless.

Example

Let’s do a sample cost comparison of Amazon EMR on EC2 and EMR Serverless using a single cluster.

We ran a Spark application on an EMR cluster with five nodes (one primary, two core, and two task and gathered YARN metrics using the YARN CLI. The following code shows our aggregate resource allocation.

aggregate resource allocation

We computed the Amazon EMR on EC2 costs as follows:

  • Cluster instances
    • Primary: m5.2xlarge:1
    • Core: r5.2xlarge:2
    • Task: r5.2xlarge:2
  • Cluster runtime = 18 min
  • Instance on-demand cost
    • m5.2xlarge (8 vCPU, 32 GiB memory)
      • Amazon EC2: $0.384/hr
      • Amazon EMR incremental: $0.096/hr
    • r5.2xlarge (8 vCPU, 64 GiB memory)
      • Amazon EC2: $0.504/hr
      • Amazon EMR incremental: $0.126/hr

The following is the EMR on EC2 cost calculation:

  • Amazon EMR cost = ((1 primary node x $0.096/hr) + (2 core nodes x $ 0.126/hr) + (2 task nodes x $0.126/hr)) = $0.60
  • Amazon EC2 cost = ((1 primary x $0.384 /hr ) + (2 core nodes x $0.504/hr) + (2 task nodes x $0.504/hr)) = $2.40
  • Amazon EMR on EC2 cluster cost/hr = $0.6 + $2.40 = $3/hr * 8/60 hr (runtime in hrs)

The total Amazon EMR on Amazon EC2 cost is $0.40/hr.

To calculate EMR Serverless cost, aggregate the vCore-seconds and memory MB-seconds for the same application you ran previously on the EMR cluster. Then multiply those numbers with the EMR Serverless vCPU and memory price. Our calculation results are as follows:

  • Total_vcore_seconds = 5737
  • Total_Memory_mb_seconds = 120156631
  • Convert to vCPU/hr and memory-GB/hr:
    • Aggregated vCPU/hr: 5737/(60*60)=1.59
    • Aggregated memory/hr: 120156631/(60*60*1024)=32.5
  • Total vCPU-hours cost = 33 vCPU * 0.052624 VCPU/hr * 8/60 = $0.23
  • Total memory GB cost = 1.59 MB * 0.0057785 memory/hr * 8/60 = $0.00122

In this example, the total EMR Serverless cost is $0.231, a 42% reduction.

Conclusion

Amazon EMR Serverless is a recently launched serverless option in Amazon EMR that makes it easy to run open-source frameworks such as Spark and Hive without configuring, managing, and scaling clusters. Customers that already use EMR clusters want to understand how they can estimate the cost of running their EMR applications using EMR Serverless. We have presented an approach that you can use to conduct a cost analysis based on analyzing application metrics from your EMR clusters.

We hope you give this a try, and share your feedback with us!


About the authors

Radhika Ravirala is the Principal Product Manager at AWS.

Matthew Liem is the Senior Solution Architecture Manager at AWS.

Architecture patterns for consuming private APIs cross-account

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/architecture-patterns-for-consuming-private-apis-cross-account/

This blog written by Thomas Moore, Senior Solutions Architect and Josh Hart, Senior Solutions Architect.

Amazon API Gateway allows developers to create private REST APIs that are only accessible from a virtual private cloud (VPC). Traffic to the private API uses secure connections and does not leave the AWS network, meaning AWS isolates it from the public internet. This makes private API Gateway endpoints a good fit for publishing internal APIs, such as those used by backend microservice communication.

In microservice architectures, where multiple teams build and manage components, different AWS accounts often consume private API endpoints.

This blog post shows how a service can consume a private API Gateway endpoint that is published in another AWS account securely over AWS PrivateLink.

Consuming API Gateway private endpoint cross-account via AWS PrivateLink.

Consuming API Gateway private endpoint cross-account via AWS PrivateLink.

This blog covers consuming API Gateway endpoints cross-account. For exposing cross-account resources behind an API Gateway, read this existing blog post.

Overview

To access API Gateway private endpoints, you must create an interface VPC endpoint (named execute-api) inside your VPC. This creates an AWS PrivateLink connection between your AWS account VPC and the API Gateway service VPC. The PrivateLink connection allows traffic to flow over private IP address space without traversing the internet.

PrivateLink allows access to private API Gateway endpoints in different AWS accounts, without VPC peering, VPN connections, or AWS Transit Gateway. A single execute-api endpoint is used to connect to any API Gateway, regardless of which AWS account the destination API Gateway is in. Resource policies control which VPC endpoints have access to the API Gateway private endpoint. This makes the cross-account architecture simpler, with no complex routing or inter-vpc connectivity.

The following diagram shows how interface VPC endpoints in a consumer account create a PrivateLink connection back to the API Gateway service account VPC. The resource policy applied to the private API determines which VPC endpoint can access the API. For this reason, it is critical to ensure that the resource policy is correct to prevent unintentional access from other AWS account VPC endpoints.

Access to private API Gateway endpoints requires an AWS PrivateLink connection to an AWS service account VPC.

Access to private API Gateway endpoints requires an AWS PrivateLink connection to an AWS service account VPC.

In this example, the resource policy denies all connections to the private API endpoint unless the aws:SourceVpce condition matches vpce-1a2b3c4d in account A. This means that connections from other execute-api VPC endpoints are denied. To allow access from account B, add vpce-9z8y7x6w to the resource policy. Refer to the documentation to learn about other condition keys you can use in API Gateway resource policies.

For more detail on how VPC links work, read Understanding VPC links in Amazon API Gateway private integrations.

The following sections cover three architecture patterns to consume API Gateway private endpoints cross-account:

  1. Regional API Gateway to private API Gateway
  2. Lambda function calling API Gateway in another account
  3. Container microservice calling API Gateway in another account using mTLS

Regional API Gateway to private API Gateway cross-account

When building microservices in different AWS accounts, private API Gateway endpoints are often used to allow service-to-service communication. Sometimes a portion of these endpoints must be exposed publicly for end user consumption. One pattern for this is to have a central public API Gateway, which acts as the front-door to multiple private API Gateway endpoints. This allows for central governance of authentication, logging and monitoring.

The following diagram shows how to achieve this using a VPC link. VPC links enable you to connect API Gateway integrations to private resources inside a VPC. The API Gateway VPC interface endpoint is the VPC resource that you want to connect to, as this is routing traffic to the private API Gateway endpoints in different AWS accounts.

API Gateway Regional endpoint consuming API Gateway private endpoints cross-account

API Gateway Regional endpoint consuming API Gateway private endpoints cross-account

VPC link requires the use of a Network Load Balancer (NLB). The target group of the NLB points to the private IP addresses of the VPC endpoint, normally one for each Availability Zone. The target group health check must validate the API Gateway service is online. You can use the API Gateway reserved /ping path for this, which returns an HTTP status code of 200 when the service is healthy.

You can deploy this pattern in your own account using the example CDK code found on GitHub.

Lambda function calling private API Gateway cross-account

Another popular requirement is for AWS Lambda functions to invoke private API Gateway endpoints cross-account. This enables service-to-service communication in microservice architectures.

The following diagram shows how to achieve this using interface endpoints for Lambda, which allows access to private resources inside your VPC. This allows Lambda to access the API Gateway VPC endpoint and, therefore, the private API Gateway endpoints in another account.

Consuming API Gateway private endpoints from Lambda cross-account

Consuming API Gateway private endpoints from Lambda cross-account

Unlike the previous example, there is no NLB or VPC link required. The resource policy on the private API Gateway must allow access from the VPC endpoint in the account where the consuming Lambda function is.

As the Lambda function has a VPC attachment, it will use DNS resolution from inside the VPC. This means that if you selected the Enable Private DNS Name option when creating the interface VPC endpoint for API Gateway the https://{restapi-id}.execute-api.{region}.amazonaws.com endpoint will automatically resolve to private IP addresses. Note that this DNS configuration can block access from Regional and edge-optimized API endpoints from inside the VPC. For more information, refer to the knowledge center article.

You can deploy this pattern in your own account using the sample CDK code found on GitHub.

Calling private API Gateway cross-account with mutual TLS (mTLS)

Customers that operate in regulated industries, such as open banking, must often implement mutual TLS (mTLS) for securely accessing their APIs. It is also great for Internet of Things (IoT) applications to authenticate devices using digital certificates.

Mutual TLS (mTLS) verifies both the client and server via certificates with TLS

Mutual TLS (mTLS) verifies both the client and server via certificates with TLS

Regional API Gateway has native support for mTLS but, currently, private API Gateway does not support mTLS, so you must terminate mTLS before the API Gateway. One pattern is to implement a proxy service in the producer account that resolves the mTLS handshake, terminates mTLS, and proxies the request to the private API Gateway over regular HTTPS.

The following diagram shows how to use a combination of PrivateLink, an NGINX-based proxy, and private API Gateway to implement mTLS and consume the private API across accounts.

Consuming API Gateway private endpoints cross-account with mTLS

Consuming API Gateway private endpoints cross-account with mTLS

In this architecture diagram, Amazon ECS Fargate is used to host the container task running the NGINX proxy server. This proxy validates the certificate passed by the connecting client before passing the connection to API Gateway via the execute-proxy VPC endpoint. The following sample NGINX configuration shows how the mTLS proxy service works by using ssl_verify_client and ssl_client_certificate settings to verify the connecting client’s certificate, and proxy_pass to forward the request onto API Gateway.

server {
    listen 443 ssl;

    ssl_certificate     /etc/ssl/server.crt;
    ssl_certificate_key /etc/ssl/server.key;
    ssl_protocols       TLSv1.2;
    ssl_prefer_server_ciphers on;
    ssl_ciphers ECDH+AESGCM:ECDH+AES256:ECDH+AES128:DH+3DES:!ADH:!AECDH:!MD5;

    ssl_client_certificate /etc/ssl/client.crt;
    ssl_verify_client      on;

    location / {
        proxy_pass https://{api-gateway-endpoint-api};
    }
}

The connecting client must supply the client certificate when connecting to the API via the VPC endpoint service:

curl --key client.key --cert client.crt --cacert server.crt https://{vpc-endpoint-service-url}

Use VPC security group rules on both the VPC endpoint and the NGINX proxy to prevent clients bypassing the mTLS endpoint and connecting directly to the API Gateway endpoint.

There is an example NGINX config and Dockerfile to configure this solution in the GitHub repository.

Conclusion

This post explores three solutions to consume private API Gateway across AWS accounts. A key component of all the solutions is the VPC interface endpoint. Using VPC Endpoints & PrivateLink, you can consume resources securely and even your own microservices across AWS accounts. For more details, read Enabling New SaaS Strategies with AWS PrivateLink. Visit the GitHub repository to get started implementing one of these solutions today.

For more serverless learning resources, visit Serverless Land.

Chaos experiments using AWS Step Functions and AWS Fault Injection Simulator

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/chaos-experiments-using-aws-step-functions-and-aws-fault-injection-simulator/

This post is written by Arunsingh Jeyasingh Jacob, Senior Solutions Architect, and Sindhura Palakodety, Senior Solutions Architect.

To run business-critical applications at scale, it is important to determine the resiliency of the application. Chaos experiments induce controlled failures into a distributed application to gain confidence in the application behavior. The learnings from these experiments can be fed into a continuous feedback cycle to improve the resiliency.

In 2021, AWS launched AWS Fault Injection Simulator (FIS). This is a fully managed service for running Fault Injection experiments on AWS. It makes it easier to improve an application’s performance, observability, and resiliency. With Fault Injection Simulator, AWS customers can quickly set up experiments using pre-built templates that generate the desired disruptions.

Overview

This post uses AWS Step Functions to create and run AWS Fault Injection Simulator (FIS) experiments. You are encouraged to perform these experiments in a test account. Do not use the example in a production environment without making appropriate code changes.

The demo-fis-stepfunctions code deployed in this post is used to build the Step Functions state machine for FIS experiments.

There are two Step Functions workflows that are deployed. One is for chaos testing Amazon EC2 workloads and the other one is for Amazon ECS workloads.

The Step Functions workflow for EC2 workloads

The following Step Functions workflow shows an EC2 chaos experiment to stress CPU utilization, and stop and terminate EC2 instances.

Step Functions workflow for Amazon EC2 Fault Injection Experiments

EC2 experiment templates

This workflow runs through FIS experiment template creation followed by the execution of the FIS experiment. The FIS experiment template contains one or more actions to run on specified targets during an experiment. By creating a template, you are not running experiments against any workload, but creating a definition for the experiment.

The EC2 experiment templates created in this workflow are:

  • EC2CPUStressExperimentTemplate
  • EC2StopExperimentTemplate
  • EC2TerminateExperimentTemplate

These are the terms used in the FIS experiment template:

  • Actions: While creating an experimentation template, you must define an action once during an experiment.
  • Targets: A target is one or more AWS resources on which an action is performed by AWS Fault Injection Simulator (AWS FIS) during an experiment. For example, defining which instances to stress CPUs based on the tags.
  • Filters: Resource filters are queries that identify target resources according to specific attributes.
  • IAM role: This IAM role is assumed by FIS to perform the actions mentioned in the template. The Step Functions role must pass permissions to this FIS role.
  • Client token: The Step Functions execution fails if a client token is not passed.
  • Selection mode: Run experiments on all the resources matching the target criteria or specify the number of resources. For example, the EC2CPUStressExperimentTemplate targets one resource in random.

The ‘EC2CPUStressExperimentTemplate’ code defines how to stop EC2 instances with the tag ‘FISAction: CPUStress’:

{
   "Targets": {
      "CPUStressInstances": {
         "ResourceType": "aws:ec2:instance",
         "ResourceTags": {
            "FISAction": "CPUStress"
         },
         "Filters": [
            {
               "Path": "VpcId",
               "Values": [
                  "${VpcID}"
               ]
            }
         ],
         "SelectionMode": "COUNT(1)"
      }
   }
}

Targets can also be filtered using parameters like Amazon VPC ID. You can change the Step Functions definition by modifying the targets, actions, and filters.

EC2 FIS experiments

FIS experiment uses the experiment template definition during the state execution, and targets the appropriate resources.

  1. There are three EC2 FIS experiments created as a part of the workflow:1. CPUStressInstances: This runs after the ‘EC2CPUStressExperimentTemplate’ state. In this state, AWS Systems Manager (SSM) attempts to add CPU stress on the target instance with the tag “FISAction: CPUStress”. You can monitor the metric in the Amazon CloudWatch dashboard, and take actions using Amazon CloudWatch alarms.
    Monitoring the CPU utilization using Amazon CloudWatch
  2. StopInstances: Here, the target instances enter the ‘stopping’ state. Based on the template definition, all the EC2 instances with the tag “FISAction:Stop” in the filtered VPC are stopped.
  3.  TerminateInstances: This terminates the target instances with the tag “FISAction:Terminate” in the filtered VPC.

The Step Functions workflow for Amazon ECS workloads

The following Step Functions workflow shows an FIS experiment to stop ECS tasks:

Step Functions workflow for Amazon ECS Fault Injection experiment

  • Amazon ECS experiment template: The ECSStopTaskExperimentTemplate state is created in this workflow. This FIS template defines the action to be run during the experiment.
  • Amazon ECS experiments: After creating the experiment template, the ECSStopTask state runs the FIS experiment.
  • ECSStopTask: FIS targets all the Amazon ECS tasks with the tag “FISAction: StopECSTask” and stops the tasks.

After the FIS experiment state is initiated, the status of the experiment can be polled before proceeding to the next state. The FIS experiments have multiple states like pending, initiating, running, completed, stopping, stopped, and failed.

The choice state in the workflow checks for the ‘running’ state by polling the status using FIS: GetExperiment API. A ‘failed’ status will result in the workflow failure. You can also design the workflow by introducing wait times between the experiments or by including flow activities like parallel.

Deploying with the AWS Serverless Application Model

This example has the following prerequisites:

  1. Create an AWS account if you don’t have one already.
  2. A valid existing VPC with subnets.
  3. A local install of Git CLI.
  4. A local install of AWS SAM CLI to build and deploy the sample code.

After installation, follow these steps to deploy the example:

  1. Clone the sample code:
    git clone https://github.com/aws-samples/aws-stepfunctions-examples.git
    cd sam/demo-fis-stepfunctions/
    
  2. Modify the templates as needed. You can also edit the state machine code from the AWS Management Console after you deploy this code.
  3. Build and deploy the code:
    sam build 
    sam deploy --guided
    

To learn more, visit the AWS SAM deployment documentation. This launches an AWS CloudFormation stack that creates the state machine, AWS IAM roles and CloudWatch log group. The next step is to run the state machines.

Running the Step Functions workflows

The AWS SAM deployment creates two Step Functions state machines in the deployed AWS Region: FISTest-aws-region-StateMachineFIS and FISTest-aws-region-StateMachineECSFIS.

Before running the state machine FISTest-aws-region-StateMachineFIS, create three EC2 instances with the tags “FISAction: CPUStress”, “FISAction:Stop” and “FISAction:Terminate” respectively.

  1. Navigate to the Step Functions console.
  2. Choose FISTest-aws-region-StateMachineFIS then Start execution.

As the workflow progresses, CPU Utilization spikes in one Amazon EC2 instance. The other Amazon EC2 instances are stopped and terminated.

To run chaos experiments on an ECS cluster, you can either use an existing ECS cluster or create a new cluster. To create an ECS cluster:

  1. Navigate to the ECS console.
  2. Choose Get Started.
  3. Choose sample-app and follow the instructions to deploy. Wait for the cluster to be created.
  4. Choose the sample cluster, then choose Tasks.
  5. Choose the running tasks and add the tag “FISAction: StopECSTask”

From the browser, the public IP assigned to the task takes you to the sample application.

Amazon ECS Sample Application

  1. Navigate to the Step Functions console.
  2. Choose FISTest-aws-region-StateMachineECSFIS, then Start execution.
  3. The workflow transitions to Wait during the execution.

Execution - FIS Step Functions workflow for ECS experiment

Once the execution is complete, the webpage momentarily becomes unavailable until a new task comes up. The public IP address and ARN of the task changes. The task status of the stopped tasks now shows “Task stopped by AWS FIS”.

ECS Task stopped by AWS FIS Experiment

To perform an FIS experiment against an existing ECS cluster, add the Resource Tags value “FISAction: StopECSTask” to your ECS tasks before running the workflows.

{
   "Targets": {
      "ecsfargatetask": {
         "ResourceType": "aws:ecs:task",
         "ResourceTags": {
            "FISAction": "StopECSTask"
         },
         "SelectionMode": "ALL"
      }
   }
}

Cleanup

If you have deployed the code using AWS SAM, delete the resources:

sam delete –stack-name <STACK_NAME>

Refer to this documentation for further information.

Conclusion

This blog post describes how to use Step Functions to orchestrate Fault Injection Simulator (FIS) experiments for EC2 and ECS workloads. Using the workflow in this post as an example, you can build state machines for more AWS FIS experiments. Step Functions, AWS FIS, and other services can be combined to build resiliency workflows, and test your application against your resiliency goals.

To learn more about AWS FIS and Step Functions, visit:

For more Step Functions resources, visit the Serverless Workflows Collection.

Visualizing the impact of AWS Lambda code updates

Post Syndicated from David Boyne original https://aws.amazon.com/blogs/compute/visualizing-the-impact-of-aws-lambda-code-updates/

This post is written by Brigit Brown (Solutions Architect), and Helen Ashton (Observability Specialist Solutions Architect).

When using AWS Lambda, changes made to code can impact performance, functionality, and cost. It can be challenging to gain insight into how these code changes impact performance.

This blog post demonstrates how to capture, record, and visualize Lambda code deployment data with other data in an Amazon CloudWatch dashboard. This solution enables serverless developers to gain insight into the impact of code changes to Lambda functions and make data-driven decisions.

There are three steps to this solution:

  1. Capture: Lambda function code updates using Amazon EventBridge.
  2. Record: Lambda function code updates by creating an Amazon CloudWatch metric.
  3. Visualize: The relationship between Lambda function code updates and application KPIs by creating a CloudWatch dashboard.

Overview

EventBridge and CloudWatch are used to monitor and visualize the impact of code changes to Lambda functions on key application metrics.

Architecture diagram for capturing, recording, and visualizing Lambda function updates, showing the AWS Lambda function event being detected by Amazon EventBridge, and finally being sent to Amazon CloudWatch

Step 1: Capturing

AWS CloudTrail records all management events for AWS services. These are the operations performed on resources in your AWS account and include Lambda function code updates.

An EventBridge rule can listen for Lambda functions code updates and send these events to other AWS services, in this case to CloudWatch.

You can create EventBridge rules using an example event syntax as reference. To get the example event, update the code of a Lambda function and search in CloudTrail for all events with Event source of lambda.amazonaws.com, and an Event name starting with UpdateFunctionCode. UpdateFunctionCode is one of many events captured for Lambda functions. For example:

{
  "eventVersion": "1.08",
  "userIdentity": {
    "type": "AssumedRole",
    "principalId": "x",
    "arn": "arn:aws:sts::xxxxxxxxxxxx:assumed-role/Admin/x",
    "accountId": "xxxxxxxxxxxx",
    "accessKeyId": "xxxxxxxxxxxxxxxxx",
    "sessionContext": {
      "sessionIssuer": {
        "type": "Role",
        "principalId": "x",
        "arn": "arn:aws:iam::xxxxxxxxxxxx:role/Admin",
        "accountId": "xxxxxxxxxxxx",
        "userName": "Admin"
      },
      "webIdFederationData": {},
      "attributes": {
        "creationDate": "2022-09-22T16:37:04Z",
        "mfaAuthenticated": "false"
      }
    }
  },
  "eventTime": "2022-09-22T16:42:07Z",
  "eventSource": "lambda.amazonaws.com",
  "eventName": "UpdateFunctionCode20150331v2",
  "awsRegion": "us-east-1",
  "sourceIPAddress": "AWS Internal",
  "userAgent": "AWS Internal",
  "requestParameters": {
    "fullyQualifiedArn": {
      "arnPrefix": {
        "partition": "aws",
        "region": "us-east-1",
        "account": "xxxxxxxxxxxx"
      },
      "relativeId": {
        "functionName": "example-function"
      },
      "functionQualifier": {}
    },
    "functionName": "arn:aws:lambda:us-east-1:xxxxxxxxxxxx:function:example-function",
    "publish": false,
    "dryRun": false
  },
  "responseElements": {
    "functionName": "example-function",
    "functionArn": "arn:aws:lambda:us-east-1:xxxxxxxxxxxx:function:example-function",
    "runtime": "python3.8",
    "role": "arn:aws:iam::xxxxxxxxxxxx:role/role-name",
    "handler": "lambda_function.lambda_handler",
    "codeSize": 1011,
    "description": "",
    "timeout": 123,
    "memorySize": 128,
    "lastModified": "2022-09-22T16:42:07.000+0000",
    "codeSha256": "x",
    "version": "$LATEST",
    "environment": {},
    "tracingConfig": {
      "mode": "PassThrough"
    },
    "revisionId": "x",
    "state": "Active",
    "lastUpdateStatus": "InProgress",
    "lastUpdateStatusReason": "The function is being created.",
    "lastUpdateStatusReasonCode": "Creating",
    "packageType": "Zip",
    "architectures": ["x86_64"],
    "ephemeralStorage": {
      "size": 512
    }
  },
  "requestID": "f566f75f-a7a8-4e87-a177-2db001d40382",
  "eventID": "4f90175d-3063-49b4-a467-04150b418457",
  "readOnly": false,
  "eventType": "AwsApiCall",
  "managementEvent": true,
  "recipientAccountId": "113420664689",
  "eventCategory": "Management",
  "sessionCredentialFromConsole": "true"
}

The key fields are eventSource, eventName, functionName, and eventType. This is the event syntax containing only the key fields.

{
    "eventSource": "lambda.amazonaws.com",
    "eventName": "UpdateFunctionCode20150331v2",
    "responseElements": {
        "functionName": "example-function"
        }
    "eventType": "AwsApiCall",
}

Use this example event as a reference to write the EventBridge rule pattern.

{
  "source": ["aws.lambda"],
  "detail-type": ["AWS API Call via CloudTrail"],
  "detail": {
    "eventSource": ["lambda.amazonaws.com"],
    "eventName": [{
      "prefix": "UpdateFunctionCode"
    }],
    "eventType": ["AwsApiCall"]
  }
}

In this EventBridge rule, the detail section contains properties to match the original UpdateFunctionCode event pattern. The values to match are in square brackets using EventBridge syntax.

The eventName changes with each UpdateFunctionCode event, including date and version information within the value (i.e. UpdateFunctionCode20150331v2) and so a prefix matching filter is used to match the start of the eventName.

The source and the detail-type of the event are two additional fields included by EventBridge. For all Lambda CloudTrail calls, the detail-type is [“AWS API Call via CloudTrail”] and the source is “aws.lambda“.

Next, send an event to CloudWatch. Each EventBridge rule can send events to multiple targets, including Amazon SNS and CloudWatch log groups. Choose a target of CloudWatch log groups, with the log group specified as /aws/events/lambda/updates. EventBridge creates this log group in CloudWatch.

Finally, test the EventBridge rule.

  1. To trigger an event, change the code for any Lambda function and deploy.

    AWS Console

  2. To view the event, navigate to the CloudWatch console > Logs > Log groups.

    Log group


  3. Choose the log group (/aws/events/lambda/updates).

    Selected log group

  4. Select the most recent log stream.

    Recent log stream

  5. If the EventBridge rule is successful, the Lambda code update event is visible. To see the JSON from the event, expand the event with the arrows to the left and see the detail field.

    Expanded view of event

Step 2: Recording

To display the Lambda function update data alongside other CloudWatch metrics, convert the log event into a metric using metric filters. A metric filter is created on a log group. If a log event matches a metric filter, a metric data point is created.

A metric filter uses a filter pattern to match on specific fields in the JSON event. In this case, the filter pattern matches on the eventName starting with UpdateFunctionCode (note the star as a wildcard).

{ $.detail.eventName=UpdateFunctionCode* }

Create a metric filter with the following:

  • Metric namespace: LambdaEvents
  • Metric name: UpdateFunction
  • Metric value: 1
  • Dimensions: DimensionName: FunctionName; Dimension Value: $.detail.responseElements.functionName

Dimensions allow metadata to be added to metrics. Setting a dimension with the JSON path to $.detail.responseElements.functionName allows the FunctionName value to come from the data in the log event. This makes this a generic metric filter for any Lambda function.

The event pattern of a metric filter can be tested on real data in the Test pattern section. Choose the log stream to test the filter on by using the Select log data drop down and selecting Test pattern. This shows a table with the matched events and the field value.

The CloudWatch console provides a view of the metrics for Lambda functions. To see the metric data, update the code for a Lambda function and navigate to the CloudWatch console. Choose Metrics > All metrics from the left menu, the Custom namespace of LambdaEvents, and dimension of FunctionName (as set in the preceding metric filter). To see the data on the chart, check the box beside the metric of interest. The metric can be added to a CloudWatch dashboard under the Actions menu.

Metric filters only create metrics when a new log event is ingested. You must wait for a new log event to see the metrics.

Step 3: Visualizing

A CloudWatch dashboard enables the visualization of metric data and creation of customized views. The dashboard can contain multiple widgets with data from metrics, logs, and alarms.

The following dashboard shows an example of visualizing Lambda code updates alongside other performance data. There is no single visualization that is right for everyone. The data added to the dashboard depends on the questions and actions the business wants to take. This data can be varied and include performance data, KPIs, and user experience.

The dashboard displays data on Lambda function code updates and Lambda performance (duration). A metric line widget shows a time chart of Lambda function duration with the update Lambda code metric data. Duration is a performance metric that is provided for all Lambda functions. Read more in Working with Lambda Function metrics.

A CloudWatch dashboard showing visualization of Lambda update code events alongside Lambda function durations for two functions. The duration is shown as an average value for the last hour and a time chart.

This screenshot shows the Lambda function duration for two different functions: PlaceOrder and AddToBasket. The duration for each function is represented in two ways:

  • A single number showing the average duration in the last hour.
  • A chart of the duration over time.

The Lambda function update event is shown on the duration time chart as an orange dot. The different views of duration show a high-level value and the detailed behavior over time. The detailed behavior is important to understanding the outcome. With only the high-level value, it is difficult to see if an increase in the hourly duration results from a short-term increase in duration, an upward trend, or a step change in behavior.

What is clear from this dashboard is that immediately following an update to the Lambda code, the PlaceOrder function duration dramatically increases from an average of ~100ms to ~300ms. This is a step change in behavior. The same deployment does not have the same impact on the duration of the AddToBasket function. While the duration is increasing near the end of the time period, it is less clear that this is because of the deployment. This dashboard provides awareness to the impact of the change at a function level so that the business can decide if the impact is acceptable.

Resources for creating your own dashboard

Conclusion

This blog demonstrates how to create an EventBridge rule and CloudWatch dashboard to visualize the impact of Lambda function code changes on performance data. First, an EventBridge rule is created to capture Lambda function code update events recorded in CloudTrail. EventBridge sends the event to CloudWatch where UpdateFunctionCode events are stored as a metric. The UpdateFunctionCode event data is visualized in a CloudWatch dashboard alongside Lambda performance data. This visibility enables teams to better understand the impact of code changes and make data-driven solutions.

You can modify the concepts in this blog and apply them to a wide variety of use cases. EventBridge can capture AWS CodeCommit and AWS CloudFormation deployments, and send the events to a CloudWatch dashboard to visualize alongside other metrics.

For more serverless learning resources, visit Serverless Land.

Let’s Architect! Optimizing the cost of your architecture

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-optimizing-the-cost-of-your-architecture/

Written in collaboration with Ben Moses, AWS Senior Solutions Architect, and Michael Holtby, AWS Senior Manager Solutions Architecture


Designing an architecture is not a simple task. There are many dimensions and characteristics of a solution to consider, such as the availability, performance, or resilience.

In this Let’s Architect!, we explore cost optimization and ideas on how to rethink your AWS workloads, providing suggestions that span from compute to data transfer.

Migrating AWS Lambda functions to Arm-based AWS Graviton2 processors

AWS Graviton processors are custom silicon from Amazon’s Annapurna Labs. Based on the Arm processor architecture, they are optimized for performance and cost, which allows customers to get up to 34% better price performance.

This AWS Compute Blog post discusses some of the differences between the x86 and Arm architectures, as well as methods for developing Lambda functions on Graviton2, including performance benchmarking.

Many serverless workloads can benefit from Graviton2, especially when they are not using a library that requires an x86 architecture to run.

Take me to this Compute post!

Choosing Graviton2 for AWS Lambda function in the AWS console

Choosing Graviton2 for AWS Lambda function in the AWS console

Key considerations in moving to Graviton2 for Amazon RDS and Amazon Aurora databases

Amazon Relational Database Service (Amazon RDS) and Amazon Aurora support a multitude of instance types to scale database workloads based on needs. Both services now support Arm-based AWS Graviton2 instances, which provide up to 52% price/performance improvement for Amazon RDS open-source databases, depending on database engine, version, and workload. They also provide up to 35% price/performance improvement for Amazon Aurora, depending on database size.

This AWS Database Blog post showcases strategies for updating RDS DB instances to make use of Graviton2 with minimal changes.

Take me to this Database post!

Choose your instance class that leverages Graviton2, such as db.r6g.large (the “g” stands for Graviton2)

Choose your instance class that leverages Graviton2, such as db.r6g.large (the “g” stands for Graviton2)

Overview of Data Transfer Costs for Common Architectures

Data transfer charges are often overlooked while architecting an AWS solution. Considering data transfer charges while making architectural decisions can save costs. This AWS Architecture Blog post describes the different flows of traffic within a typical cloud architecture, showing where costs do and do not apply. For areas where cost applies, it shows best-practice strategies to minimize these expenses while retaining a healthy security posture.

Take me to this Architecture post!

Accessing AWS services in different Regions

Accessing AWS services in different Regions

Improve cost visibility and re-architect for cost optimization

This Architecture Blog post is a collection of best practices for cost management in AWS, including the relevant tools; plus, it is part of a series on cost optimization using an e-commerce example.

AWS Cost Explorer is used to first identify opportunities for optimizations, including data transfer, storage in Amazon Simple Storage Service and Amazon Elastic Block Store, idle resources, and the use of Graviton2 (Amazon’s Arm-based custom silicon). The post discusses establishing a FinOps culture and making use of Service Control Policies (SCPs) to control ongoing costs and guide deployment decisions, such as instance-type selection.

Take me to this Architecture post!

Applying SCPs on different environments for cost control

Applying SCPs on different environments for cost control

See you next time!

Thanks for joining us to discuss optimizing costs while architecting! This is the last Let’s Architect! post of 2022. We will see you again in 2023, when we explore even more architecture topics together.

Wishing you a happy holiday season and joyous new year!

Can’t get enough of Let’s Architect!?

Visit the Let’s Architect! page of the AWS Architecture Blog for access to the whole series.

Looking for more architecture content?

AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

Securing Lambda Function URLs using Amazon Cognito, Amazon CloudFront and AWS WAF

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/compute/securing-lambda-function-urls-using-amazon-cognito-amazon-cloudfront-and-aws-waf/

This post is written by Madhu Singh (Solutions Architect), and Krupanidhi Jay (Solutions Architect).

Lambda function URLs is a dedicated HTTPs endpoint for a AWS Lambda function. You can configure a function URL to have two methods of authentication: IAM and NONE. IAM authentication means that you are restricting access to the function URL (and in-turn access to invoke the Lambda function) to certain AWS principals (such as roles or users). Authentication type of NONE means that the Lambda function URL has no authentication and is open for anyone to invoke the function.

This blog shows how to use Lambda function URLs with an authentication type of NONE and use custom authorization logic as part of the function code, and to only allow requests that present valid Amazon Cognito credentials when invoking the function. You also learn ways to protect Lambda function URL against common security threats like DDoS using AWS WAF and Amazon CloudFront.

Lambda function URLs provides a simpler way to invoke your function using HTTP calls. However, it is not a replacement for Amazon API Gateway, which provides advanced features like request validation and rate throttling.

Solution overview

There are four core components in the example.

1. A Lambda function with function URLs enabled

At the core of the example is a Lambda function with the function URLs feature enabled with the authentication type of NONE. This function responds with a success message if a valid authorization code is passed during invocation. If not, it responds with a failure message.

2. Amazon Cognito User Pool

Amazon Cognito user pools enable user authentication on websites and mobile apps. You can also enable publicly accessible Login and Sign-Up pages in your applications using Amazon Cognito user pools’ feature called the hosted UI.

In this example, you use a user pool and the associated Hosted UI to enable user login and sign-up on the website used as entry point. This Lambda function validates the authorization code against this Amazon Cognito user pool.

3. CloudFront distribution using AWS WAF

CloudFront is a content delivery network (CDN) service that helps deliver content to end users with low latency, while also improving the security posture for your applications.

AWS WAF is a web application firewall that helps protect your web applications or APIs against common web exploits and bots and AWS Shield is a managed distributed denial of service (DDoS) protection service that safeguards applications running on AWS. AWS WAF inspects the incoming request according to the configured Web Access Control List (web ACL) rules.

Adding CloudFront in front of your Lambda function URL helps to cache content closer to the viewer, and activating AWS WAF and AWS Shield helps in increasing security posture against multiple types of attacks, including network and application layer DDoS attacks.

4. Public website that invokes the Lambda function

The example also creates a public website built on React JS and hosted in AWS Amplify as the entry point for the demo. This website works both in authenticated mode and in guest mode. For authentication, the website uses Amazon Cognito user pools hosted UI.

Solution architecture

This shows the architecture of the example and the information flow for user requests.

In the request flow:

  1. The entry point is the website hosted in AWS Amplify. In the home page, when you choose “sign in”, you are redirected to the Amazon Cognito hosted UI for the user pool.
  2. Upon successful login, Amazon Cognito returns the authorization code, which is stored as a cookie with the name “code”. The user is redirected back to the website, which has an “execute Lambda” button.
  3. When the user choose “execute Lambda”, the value from the “code” cookie is passed in the request body to the CloudFront distribution endpoint.
  4. The AWS WAF web ACL rules are configured to determine whether the request is originating from the US or Canada IP addresses and to determine if the request should be allowed to invoke Lambda function URL origin.
  5. Allowed requests are forwarded to the CloudFront distribution endpoint.
  6. CloudFront is configured to allow CORS headers and has the origin set to the Lambda function URL. The request that CloudFront receives is passed to the function URL.
  7. This invokes the Lambda function associated with the function URL, which validates the token.
  8. The function code does the following in order:
    1. Exchange the authorization code in the request body (passed as the event object to Lambda function) to access_token using Amazon Cognito’s token endpoint (check the documentation for more details).
      1. Amazon Cognito user pool’s attributes like user pool URL, Client ID and Secret are retrieved from AWS Systems Manager Parameter Store (SSM Parameters).
      2. These values are stored in SSM Parameter Store at the time these resources are deployed via AWS CDK (see “how to deploy” section)
    2. The access token is then verified to determine its authenticity.
    3. If valid, the Lambda function returns a message stating user is authenticated as <username> and execution was successful.
    4. If either the authorization code was not present, for example, the user was in “guest mode” on the website, or the code is invalid or expired, the Lambda function returns a message stating that the user is not authorized to execute the function.
  9. The webpage displays the Lambda function return message as an alert.

Getting started

Pre-requisites:

Before deploying the solution, please follow the README from the GitHub repository and take the necessary steps to fulfill the pre-requisites.

Deploy the sample solution

1. From the code directory, download the dependencies:

$ npm install

2. Start the deployment of the AWS resources required for the solution:

$ cdk deploy

Note:

  • optionally pass in the –profile argument if needed
  • The deployment can take up to 15 minutes

3. Once the deployment completes, the output looks similar to this:

Open the amplifyAppUrl from the output in your browser. This is the URL for the demo website. If you don’t see the “Welcome to Compute Blog” page, the Amplify app is still building, and the website is not available yet. Retry in a few minutes. This website works either in an authenticated or unauthenticated state.

Test the authenticated flow

  1. To test the authenticated flow, choose “Sign In”.

2. In the sign-in page, choose on sign-up (for the first time) and create a user name and password.

3. To use an existing an user name and password, enter those credentials and choose login.

4. Upon successful sign-in or sign up, you are redirected back to the webpage with “Execute Lambda” button.

5. Choose this button. In a few seconds, an alert pop-up shows the logged in user and that the Lambda execution is successful.

Testing the unauthenticated flow

1. To test the unauthenticated flow, from the Home page, choose “Continue”.

2. Choose “Execute Lambda” and in a few seconds, you see a message that you are not authorized to execute the Lambda function.

Testing the geo-block feature of AWS WAF

1. Access the website from a Region other than US or Canada. If you are physically in the US or Canada, you may use a VPN service to connect to a Region other than US or Canada.

2. Choose the “Execute Lambda” button. In the Network trace of browser, you can see the call to invoke Lambda function was blocked with Forbidden response.

3. To try either the authenticated or unauthenticated flow again, choose “Return to Home Page” to go back to the home page with “Sign In” and “Continue” buttons.

Cleaning up

To delete the resources provisioned, run the cdk destroy command from the AWS CDK CLI.

Conclusion

In this blog, you create a Lambda function with function URLs enabled with NONE as the authentication type. You then implemented a custom authentication mechanism as part of your Lambda function code. You also increased the security of your Lambda function URL by setting it as Origin for the CloudFront distribution and using AWS WAF Geo and IP limiting rules for protection against common web threats, like DDoS.

For more serverless learning resources, visit Serverless Land.

Introducing Serverlesspresso Extensions

Post Syndicated from Benjamin Smith original https://aws.amazon.com/blogs/compute/introducing-serverlesspresso-extensions/

Today the Serverless DA team is launching Serverlesspresso Extensions, a new program that lets you contribute to Serverlesspresso. The best extensions will be added to the Serverlesspresso application running in production and featured on the AWS Compute Blog.

What is Serverlesspresso?

Serverlesspresso is a multi-tenant event-driven serverless application for a pop-up coffee bar that allows you to order from your phone. In 2022, Serverlesspresso processed over 20,000 orders at technology events around the world. At this year’s re:Invent, it featured in the keynote of Amazon CTO, Dr Werner Vogels. It was showcased as an example of an event-driven application that can be easily evolved.

The architecture comprises several serverless apps and has been open-source and freely available since it was launched at re:Invent 2021.

What is extensibility?

Extensibility is the ability to add new functionality to an existing piece of software without modifying the core code already in place. Extensions for web browsers are an example of how useful extensibility can be. The core web browser code is not changed or affected when third parties write extensions, but end users can gain new, rich functionality not envisioned or intended by the original browser authors.

In many production business applications extensibility can help you keep up with the pace of your users requests. It allows you to create new and useful functionality without having to rearchitect the core, original part of your code. Choosing an architectural style that supports this concept can help you retain flexibility as your users needs change.

How EDA supports extensibility

Serverlesspresso is built on an event-driven architecture (EDA). This is an architecture style that uses events to decouple an application’s components. Event-driven architecture offers an effective way to create loosely coupled communication between microservices. This makes it a good architectural choice when you are designing workloads that will require extensibility.

Loosely coupled microservices are able to scale and fail independently, increasing the resilience of the application. Development teams can build and release features for their team’s microservice quickly, without needing to worry about the behavior of other microservices in the application. In addition, new features can be added on top of existing events without making changes to the rest of the application.

Choreography and orchestration are two different models for how distributed services can communicate with one another. In orchestration, communication is more tightly controlled. A central service coordinates the interaction and order in which services are invoked.

Choreography achieves communication without tight control. Events flow between services without any centralized coordination. Many applications, including Serverlesspresso use both choreography and orchestration for different use cases. Event buses such as Amazon EventBridge can be used for choreography, and workflow orchestration services like AWS Step Functions can help build for orchestration.

New functional requirements come up all the time in production applications. We can address new requirements for an event driven application by creating new rules for events in the Event Bus. These rules can add new functionality to the application without having any impact to the existing application stack.

Characteristics of a Serverlesspresso EDA extension

  1. Extension resources do not have permission to interact with resources outside the extension definition (including core app resources).
  2. Extensions must contain at least one new EventBridge rule that routes existing Serverlesspresso events.
  3. Extensions can be deployed and deleted independently of other extensions and the core application.

Building a Serverlesspresso extension

This section shows how to build an extension for Serverlesspresso that adds new functionality while remaining decoupled from the core application. Anyone can contribute an extension to Serverlesspresso. Use the Serverlesspresso extensions GitHub repository to host your extension:

  1. Complete the GitHub issue template:
  2. Clone the repository. Duplicate, and rename the example _extension_model directory.
  3. Add the associated extension template and source files.
  4. Add the required meta information to `README.md`.
  5. Make a pull request to the repository with the new extension files.

Additional guidance can be found in the repository’s PUBLISHING.md file.

Tools and resources to help you build

Event decoupling introduces a new set of challenges. Finding events and their schema can be a difficult process. Developers must coordinate with the team responsible for publishing an event, or look through documentation to find its schema, and then manually create an object for the event in order to use it in their code.

The Amazon EventBridge schema registry helps solve this challenge. It automatically finds events and their structure, or schema, and stores them in a shared central location. For serverlesspresso Extensions, we have created the Serverlesspresso events catalog, and filled it with events from the EventBridge schema registry. Here, all Serverlesspresso events have been documented to help you understand how to use them in your extensions. This includes the services that produce and consumer the event as well as example schemes for each event.

The event player

The event player is a Step Functions workflow that simulates 15 minutes of operation at the Serverlesspresso bar. It does this by replaying an array of realistic events. Use the event player to generate Serverlesspresso events, when building and testing your extensions. Each event is emitted onto an event bus named Serverlesspresso.

  1. Clone this repository: git clone https://github.com/aws-samples/serverless-coffee.git
  2. Change directory to the event player: cd extensibility/EventPlayer
  3. Deploy the EventPlayer using the AWS SAM CLI:
    sam build && sam deploy --guided

This deploys a Step Functions workflow and a custom event bus called “Serverlesspresso”

Running the events player

  1. Open the event player from the AWS Management Console.
  2. Choose Start execution, leave the default input payload and choose Start execution.

The player takes approximately 15 minutes to complete.

About your extension submission

Extensions will be reviewed by the Serverless DA team within 14 days of submission. When submitting your extension, your extension will become part of the open source offering and is covered by the existing license in the repo. It may be used by any customer under the same license. For additional guidance and ideas to help build your Serverlesspresso extensions, use the following resources:

Conclusion

You can now build extensions for Serverlesspresso, and potentially be featured on the AWS Compute Blog by submitting a Serverlesspresso extension. The best extensions will be added to Serverlesspresso in production.

Some demo extensions have been built and documented at https://github.com/aws-samples/serverless-coffee/tree/main/extensions. You can download and install these extensions to see how they are constructed before creating your own.

Visit the Serverless Workflows Collection to browse the many deployable workflows to help build your serverless applications.

Visualize and create your serverless workloads with AWS Application Composer

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/visualize-and-create-your-serverless-workloads-with-aws-application-composer/

This post is written by Luca Mezzalira, Principal Specialist Solutions Architect.

Today, AWS is launching a preview of AWS Application Composer, a visual designer that you can use to build your serverless applications from multiple AWS services.

In distributed systems, empowering teams is a cultural shift needed for enabling developers to help translate business capabilities into code.

This doesn’t mean every team works in isolation. Different teams or even new-joiners must understand what they are building to contribute to a project. The best way to understand architecture quickly is by using diagrams. Unfortunately, architectural diagrams are often outdated. Often, when releasing a workload in production, there are already discrepancies from the initial design and infrastructure.

Developers new to building serverless applications can face a learning curve when composing applications from multiple AWS services. They must understand how to configure each service, and then learn and write infrastructure as code (IaC) to deploy their application.

Example scenario

Emma is a cloud architect working for a video on-demand platform where every user can access the content after subscribing to the service. In the next few months, the marketing team wants to start a campaign to increase the user base using discount codes for new users only.

She collaborates with a team of developers who are new to building serverless applications. They must design a discount code service that can scale to thousands of transactions per second. There are many requirements to implement this service:

  • Gathering the gift code from a user.
  • Verifying the discount code is available.
  • Applying the discount code to the invoice at the end of the month.

Based on these requirements and default SLAs available for all the platform services, Emma designs a high-level architecture with the key elements needed for building this microservice.

Discount code service high-level architecture

Discount code service high-level architecture

Her idea is to receive a request from clients with a discount code in the payload, and validate the availability of the discount code in a database. The service then asynchronously processes different discount codes in batches to reduce traffic to downstream dependencies and reduce the cost of the overall infrastructure.

This approach ensures that the service can scale in the future beyond the initial traffic volume. It simplifies the management and implementation of the discount code service and other parts of the system with a loosely coupled architecture.

After discussing the architecture with her developers, she opens Application Composer in the AWS Management Console and starts building the implementation using serverless services.

Application Composer initial screen

Application Composer initial screen

To start, she selects New blank project and selects a local file system folder to save the project files.

Application Composer create blank project

Application Composer create blank project

Granting Application Composer access to your local project files allows near real time bidirectional syncing of changes between the console interface and locally stored project files. When you update a property with the Application Composer interface, it’s reflected in the files stored locally. When you change a local file in your IDE, it automatically reflects in the Application Composer canvas.

After creating the project, Emma drags the AWS resources she needs from the left sidebar for expressing the initial design agreed with the team.

Using Application Composer, you can drag serverless resources on the canvas and connect them together. In the background, Application Composer generates the infrastructure as code AWS CloudFormation template for you.

Application Composer canvas

Application Composer canvas

For example, this is the default configuration generated when you drag a Lambda function onto the canvas. The following code is present in the template view:

  Function:
    Type: AWS::Serverless::Function
    Properties:
      FunctionName: !Sub ${AWS::StackName}-Function
      Description: !Sub
        - Stack ${AWS::StackName} Function ${ResourceName}
        - ResourceName: Function
      CodeUri: src/Function
      Handler: index.handler
      Runtime: nodejs14.x
      MemorySize: 3008
      Timeout: 30
      Tracing: Active

Application Composer incorporates some helpful default property values, which are sometimes overlooked by developers new to serverless workloads. These include activating tracing using AWS X-Ray or increasing a function timeout, for instance.

You can change these parameters either in the CloudFormation template inside Application Composer or by visually selecting a resource. In the previous example, you can update the Lambda function parameters by opening the resource properties panel.

Application Composer resource panel

Application Composer resource panel

When you synchronize an Application Composer project with the local system, you can change the CloudFormation template from a code editor. This reflects the change in the Application Composer interface automatically.

When you connect two elements in the canvas, Application Composer sets default IAM policies, environment variables for Lambda functions, and event subscriptions where applicable.

For instance, if you have a Lambda function that interacts with an Amazon DynamoDB table and Amazon SQS queue, Application Composer generates the following configuration for the Lambda function.

Function:
    Type: AWS::Serverless::Function
    Properties:
      FunctionName: !Sub ${AWS::StackName}-Function
      Description: !Sub
        - Stack ${AWS::StackName} Function ${ResourceName}
        - ResourceName: Function
      CodeUri: src/Function
      Handler: index.handler
      […]
      Environment:
        Variables:
          QUEUE_NAME: !GetAtt Queue.QueueName
          QUEUE_ARN: !GetAtt Queue.Arn
          QUEUE_URL: !Ref Queue
          TABLE_NAME: !Ref Table
          TABLE_ARN: !GetAtt Table.Arn
      Policies:
        - SQSSendMessagePolicy:
            QueueName: !GetAtt Queue.QueueName
        - DynamoDBCrudPolicy:
            TableName: !Ref Table

This helps new builders when designing their first serverless applications and provides an initial configuration, which more advanced builders can amend. This allows you to include good operational practices when designing a serverless application.

Emma’s team continues to add together the different services needed to express the discount code architecture. This is the final result in Application Composer:

Discount code architecture in Application Composer

Discount code architecture in Application Composer

  1. The application includes an Amazon API Gateway endpoint that exposes the API needed for submitting a discount code to the system.
  2. The POST API triggers a Lambda function that first validates that the discount code is still available.
  3. This is stored using a DynamoDB table
  4. After successfully validating the discount code, the function adds a message to an SQS queue and returns a successful response to the client.
  5. Another Lambda function retrieves the message from the SQS queue and sends an invoice.

Using this approach optimizes the Lambda function invocation for speed as the remaining operations are handled asynchronously. This also simplifies the complexity and cost of the architecture because you can aggregate multiple discount codes per user SQS batching, rather than scaling the service when requests arrive from the users.

The team agrees to use this as the initial design of their service. In the future, they plan to integrate with their authentication mechanism. They add Lambda Powertools for observability, and additional libraries developed internally to make the project compliant with company standards.

Application Composer has created all the files needed to start the project in Emma’s local file system including the CloudFormation template .yaml file and the Lambda functions’ handlers.

Application Composer generated files

Application Composer generated files

Emma can now upload the outline of this service to a version control system and share the artifacts with other developers who can start coding the business logic.

Additional features

Application Composer includes a resource list tab within the left-side panel that allows you to quickly browse available resources.

Application Composer browse available resources

Application Composer browse available resources

You can also group resources semantically for simplifying the visualization inside the canvas. This helps when you have a large application in the canvas and you want to select an element quickly without dragging the canvas around to find the resource. This feature doesn’t impact the infrastructure generated.

Application Composer grouping

Application Composer grouping

Application Composer adds some metadata to the CloudFormation template to allow the canvas to group resources together when the project is loaded again.

Metadata:
  AWS::Composer::Groups:
    Group:
      Label: Group
      Members:
        - CodesQueue
        - CodesTable

You can use Application Composer beyond building new serverless workloads. You can load existing CloudFormation templates by selecting Load existing project in the Create project dialog.

Application Composer load existing project

Application Composer load existing project

You can use this to define your blueprints with organizational best practices and then visualize them within Application Composer. This helps teams collaborate when starting new serverless services. You can add resources from an existing base template to build serverless microservices or event-driven architectures.

Integration with AWS SAM

AWS Serverless Application Model (AWS SAM) recently announced the general availability of AWS SAM Accelerate to accelerate the feedback loop and testing of your code and cloud infrastructure by synchronizing only project changes. You can use Application Composer together with AWS SAM Accelerate to more simply visually build and then test your serverless applications in the cloud.

To learn more about AWS SAM Accelerate, watch this live demo.

Where Application Composer fits into the development process

Emma used Application Composer to help her team for this project but has ideas on further ways to use it.

  • Rapid prototyping.
  • Reviewing and collaboratively evolving existing serverless projects.
  • Generating diagrams for documentation or Wikis.
  • On-boarding new team members to a project
  • Reducing the first steps to deploy something in an AWS Cloud account.

Application Composer availability

Application Composer is currently available as a public preview in the following Regions: Frankfurt (eu-central-1), Ireland (eu-west-1), Ohio (us-east-2), Oregon (us-west-2), North Virginia (us-east-1) and Tokyo (ap-northeast-1).

Application Composer is available at no additional cost and can be accessed via the AWS Management Console.

Conclusion

Application Composer is a visual designer to help developers and architects express and build their application architecture. They can iterate on their ideas with colleagues and create documentation for others working on the application for the first time. You can use Application Composer during multiple stages of your software development lifecycle, reducing the friction in getting your project started and into production.

Currently, Application Composer supports a limited number of services that we plan to add to in the future. Let us know which services you would like to see included.

As a public preview, we are looking for suggestions and ideas to evolve the tool. We are looking for ways to help you and your teams to speed up the adoption of serverless workloads inside your organization. Add a comment to this post or tweet with the tag #AWSAppComposerWishlist.

For more serverless learning resources, visit Serverless Land.

Introducing the Cloud Shuffle Storage Plugin for Apache Spark

Post Syndicated from Noritaka Sekiyama original https://aws.amazon.com/blogs/big-data/introducing-the-cloud-shuffle-storage-plugin-for-apache-spark/

AWS Glue is a serverless data integration service that makes it easy to discover, prepare, and combine data for analytics, machine learning (ML), and application development. In AWS Glue, you can use Apache Spark, an open-source, distributed processing system for your data integration tasks and big data workloads.

Apache Spark utilizes in-memory caching and optimized query execution for fast analytic queries against your datasets, which are split into multiple Spark partitions on different nodes so that you can process a large amount of data in parallel. In Apache Spark, shuffling happens when data needs to be redistributed across the cluster. During a shuffle, data is written to local disk and transferred across the network. The shuffle operation is often constrained by the available local disk capacity, or data skew, which can cause straggling executors. Spark often throws a No space left on device or MetadataFetchFailedException error when there isn’t enough disk space left on the executor and there is no recovery. Such Spark jobs can’t typically succeed without adding additional compute and attached storage, wherein compute is often idle, and results in additional cost.

In 2021, we launched Amazon S3 shuffle for AWS Glue 2.0 with Spark 2.4. This feature disaggregated Spark compute and shuffle storage by utilizing Amazon Simple Storage Service (Amazon S3) to store Spark shuffle files. Using Amazon S3 for Spark shuffle storage enabled you to run data-intensive workloads more reliably. After the launch, we continued investing in this area, and collected customer feedback.

Today, we’re pleased to release Cloud Shuffle Storage Plugin for Apache Spark. It supports the latest Apache Spark 3.x distribution so you can take advantage of the plugin in AWS Glue or any other Spark environments. It’s now also natively available to use in AWS Glue Spark jobs on AWS Glue 3.0 and the latest AWS Glue version 4.0 without requiring any extra setup or bringing external libraries. Like the Amazon S3 shuffle for AWS Glue 2.0, the Cloud Shuffle Storage Plugin helps you solve constrained disk space errors during shuffle in serverless Spark environments.

We’re also excited to announce the release of software binaries for the Cloud Shuffle Storage Plugin for Apache Spark under the Apache 2.0 license. You can download the binaries and run them on any Spark environment. The new plugin is open-cloud, comes with out-of-the box support for Amazon S3, and can be easily configured to use other forms of cloud storage such as Google Cloud Storage and Microsoft Azure Blob Storage.

Understanding a shuffle operation in Apache Spark

In Apache Spark, there are two types of transformations:

  • Narrow transformation – This includes map, filter, union, and mapPartition, where each input partition contributes to only one output partition.
  • Wide transformation – This includes join, groupBykey, reduceByKey, and repartition, where each input partition contributes to many output partitions. Spark SQL queries including JOIN, ORDER BY, GROUP BY require wide transformations.

A wide transformation triggers a shuffle, which occurs whenever data is reorganized into new partitions with each key assigned to one of them. During a shuffle phase, all Spark map tasks write shuffle data to a local disk that is then transferred across the network and fetched by Spark reduce tasks. The volume of data shuffled is visible in the Spark UI. When shuffle writes take up more space than the local available disk capacity, it causes a No space left on device error.

To illustrate one of the typical scenarios, let’s use the query q80.sql from the standard TPC-DS 3 TB dataset as an example. This query attempts to calculate the total sales, returns, and eventual profit realized during a specific time frame. It involves multiple wide transformations (shuffles) caused by left outer join and group by.

Let’s run the following query on AWS Glue 3.0 job with 10 G1.X workers where a total of 640GB of local disk space is available:

with ssr as
 (select  s_store_id as store_id,
          sum(ss_ext_sales_price) as sales,
          sum(coalesce(sr_return_amt, 0)) as returns,
          sum(ss_net_profit - coalesce(sr_net_loss, 0)) as profit
  from store_sales left outer join store_returns on
         (ss_item_sk = sr_item_sk and ss_ticket_number = sr_ticket_number),
     date_dim, store, item, promotion
 where ss_sold_date_sk = d_date_sk
       and d_date between cast('2000-08-23' as date)
                  and (cast('2000-08-23' as date) + interval '30' day)
       and ss_store_sk = s_store_sk
       and ss_item_sk = i_item_sk
       and i_current_price > 50
       and ss_promo_sk = p_promo_sk
       and p_channel_tv = 'N'
 group by s_store_id),
 csr as
 (select  cp_catalog_page_id as catalog_page_id,
          sum(cs_ext_sales_price) as sales,
          sum(coalesce(cr_return_amount, 0)) as returns,
          sum(cs_net_profit - coalesce(cr_net_loss, 0)) as profit
  from catalog_sales left outer join catalog_returns on
         (cs_item_sk = cr_item_sk and cs_order_number = cr_order_number),
     date_dim, catalog_page, item, promotion
 where cs_sold_date_sk = d_date_sk
       and d_date between cast('2000-08-23' as date)
                  and (cast('2000-08-23' as date) + interval '30' day)
        and cs_catalog_page_sk = cp_catalog_page_sk
       and cs_item_sk = i_item_sk
       and i_current_price > 50
       and cs_promo_sk = p_promo_sk
       and p_channel_tv = 'N'
 group by cp_catalog_page_id),
 wsr as
 (select  web_site_id,
          sum(ws_ext_sales_price) as sales,
          sum(coalesce(wr_return_amt, 0)) as returns,
          sum(ws_net_profit - coalesce(wr_net_loss, 0)) as profit
  from web_sales left outer join web_returns on
         (ws_item_sk = wr_item_sk and ws_order_number = wr_order_number),
     date_dim, web_site, item, promotion
 where ws_sold_date_sk = d_date_sk
       and d_date between cast('2000-08-23' as date)
                  and (cast('2000-08-23' as date) + interval '30' day)
        and ws_web_site_sk = web_site_sk
       and ws_item_sk = i_item_sk
       and i_current_price > 50
       and ws_promo_sk = p_promo_sk
       and p_channel_tv = 'N'
 group by web_site_id)
 select channel, id, sum(sales) as sales, sum(returns) as returns, sum(profit) as profit
 from (select
        'store channel' as channel, concat('store', store_id) as id, sales, returns, profit
      from ssr
      union all
      select
        'catalog channel' as channel, concat('catalog_page', catalog_page_id) as id,
        sales, returns, profit
      from csr
      union all
      select
        'web channel' as channel, concat('web_site', web_site_id) as id, sales, returns, profit
      from  wsr) x
 group by rollup (channel, id)
 order by channel, id

The following screenshot shows the Executor tab in the Spark UI.
Spark UI Executor Tab

The following screenshot shows the status of Spark jobs included in the AWS Glue job run.
Spark UI Jobs
In the failed Spark job (job ID=7), we can see the failed Spark stage in the Spark UI.
Spark UI Failed stage
There was 167.8GiB shuffle write during the stage, and 14 tasks failed due to the error java.io.IOException: No space left on device because the host 172.34.97.212 ran out of local disk.
Spark UI Tasks

Cloud Shuffle Storage for Apache Spark

Cloud Shuffle Storage for Apache Spark allows you to store Spark shuffle files on Amazon S3 or other cloud storage services. This gives complete elasticity to Spark jobs, thereby allowing you to run your most data intensive workloads reliably. The following figure illustrates how Spark map tasks write the shuffle files to the Cloud Shuffle Storage. Reducer tasks consider the shuffle blocks as remote blocks and read them from the same shuffle storage.

This architecture enables your serverless Spark jobs to use Amazon S3 without the overhead of running, operating, and maintaining additional storage or compute nodes.
Chopper diagram
The following Glue job parameters enable and tune Spark to use S3 buckets for storing shuffle data. You can also enable at-rest encryption when writing shuffle data to Amazon S3 by using security configuration settings.

Key Value Explanation
--write-shuffle-files-to-s3 TRUE This is the main flag, which tells Spark to use S3 buckets for writing and reading shuffle data.
--conf spark.shuffle.storage.path=s3://<shuffle-bucket> This is optional, and specifies the S3 bucket where the plugin writes the shuffle files. By default, we use –TempDir/shuffle-data.

The shuffle files are written to the location and create files such as following:

s3://<shuffle-storage-path>/<Spark application ID>/[0-9]/<Shuffle ID>/shuffle_<Shuffle ID>_<Mapper ID>_0.data

With the Cloud Shuffle Storage plugin enabled and using the same AWS Glue job setup, the TPC-DS query now succeeded without any job or stage failures.
Spark UI Jobs with Chopper plugin

Software binaries for the Cloud Shuffle Storage Plugin

You can now also download and use the plugin in your own Spark environments and with other cloud storage services. The plugin binaries are available for use under the Apache 2.0 license.

Bundle the plugin with your Spark applications

You can bundle the plugin with your Spark applications by adding it as a dependency in your Maven pom.xml as you develop your Spark applications, as shown in the follwoing code. For more details on the plugin and Spark versions, refer to Plugin versions.

<repositories>
   ...
    <repository>
        <id>aws-glue-etl-artifacts</id>
        <url>https://aws-glue-etl-artifacts.s3.amazonaws.com/release/</url>
    </repository>
</repositories>
...
<dependency>
    <groupId>com.amazonaws</groupId>
    <artifactId>chopper-plugin</artifactId>
    <version>3.1-amzn-LATEST</version>
</dependency>

You can alternatively download the binaries from AWS Glue Maven artifacts directly and include them in your Spark application as follows:

#!/bin/bash
sudo wget -v https://aws-glue-etl-artifacts.s3.amazonaws.com/release/com/amazonaws/chopper-plugin/3.1-amzn-LATEST/chopper-plugin-3.1-amzn-LATEST.jar -P /usr/lib/spark/jars

Submit the Spark application by including the JAR files on the classpath and specifying the two Spark configs for the plugin:

spark-submit --deploy-mode cluster \
--conf spark.shuffle.sort.io.plugin.class=com.amazonaws.spark.shuffle.io.cloud.ChopperPlugin \
--conf spark.shuffle.storage.path=s3://<s3 bucket>/<shuffle-dir> \
 --class <your class> <your application jar> 

The following Spark parameters enable and configure Spark to use an external storage URI such as Amazon S3 for storing shuffle files; the URI protocol determines which storage system to use.

Key Value Explanation
spark.shuffle.storage.path s3://<shuffle-storage-path> It specifies an URI where the shuffle files are stored, which much be a valid Hadoop FileSystem and be configured as needed
spark.shuffle.sort.io.plugin.class com.amazonaws.spark.shuffle.io.cloud.ChopperPlugin The entry class in the plugin

Other cloud storage integration

This plugin comes with out-of-the box support for Amazon S3 and can also be configured to use other forms of cloud storage such as Google Cloud Storage and Microsoft Azure Blob Storage. To enable other Hadoop FileSystem compatible cloud storage services, you can simply add a storage URI for the corresponding service scheme, such as gs:// for Google Cloud Storage instead of s3:// for Amazon S3, add the FileSystem JAR files for the service, and set the appropriate authentication configurations.

For more information about how to integrate the plugin with Google Cloud Storage and Microsoft Azure Blob Storage, refer to Using AWS Glue Cloud Shuffle Plugin for Apache Spark with Other Cloud Storage Services.

Best practices and considerations

Note the following considerations:

  • This feature replaces local shuffle storage with Amazon S3. You can use it to address common failures with price/performance benefits for your serverless analytics jobs and pipelines. We recommend enabling this feature when you want to ensure reliable runs of your data-intensive workloads that create a large amount of shuffle data or when you’re getting No space left on device error. You can also use this plugin if your job encounters fetch failures org.apache.spark.shuffle.MetadataFetchFailedException or if your data is skewed.
  • We recommend setting S3 bucket lifecycle policies on the shuffle bucket (spark.shuffle.storage.s3.path) in order to clean up old shuffle data automatically.
  • The shuffle data on Amazon S3 is encrypted by default. You can also encrypt the data with your own AWS Key Management Service (AWS KMS) keys.

Conclusion

This post introduced the new Cloud Shuffle Storage Plugin for Apache Spark and described its benefits to independently scale storage in your Spark jobs without adding additional workers. With this plugin, you can expect jobs processing terabytes of data to run much more reliably.

The plugin is available in AWS Glue 3.0 and 4.0 Spark jobs in all AWS Glue supported Regions. We’re also releasing the plugin’s software binaries under the Apache 2.0 license. You can use the plugin in AWS Glue or other Spark environments. We look forward to hearing your feedback.


About the Authors

Noritaka Sekiyama s a Principal Big Data Architect on the AWS Glue team. He is responsible for building software artifacts that help customers build data lakes on the cloud.

Rajendra Gujja is a Senior Software Development Engineer on the AWS Glue team. He is passionate about distributed computing and everything and anything about the data.

Chuhan Liu is a Software Development Engineer on the AWS Glue team.

Gonzalo Herreros is a Senior Big Data Architect on the AWS Glue team.

Mohit Saxena is a Senior Software Development Manager on the AWS Glue team. His team focuses on building distributed systems to enable customers with data integration and connectivity to a variety of sources, efficiently manage data lakes on Amazon S3, and optimizes Apache Spark for fault-tolerance with ETL workloads.

Log analytics the easy way with Amazon OpenSearch Serverless

Post Syndicated from Prashant Agrawal original https://aws.amazon.com/blogs/big-data/log-analytics-the-easy-way-with-amazon-opensearch-serverless/

We recently announced the preview release of Amazon OpenSearch Serverless, a new serverless option for Amazon OpenSearch Service, which makes it easy for you to run large-scale search and analytics workloads without having to configure, manage, or scale OpenSearch clusters. It automatically provisions and scales the underlying resources to deliver fast data ingestion and query responses for even the most demanding and unpredictable workloads.

OpenSearch Serverless supports two primary use cases:

  • Log analytics that focuses on analyzing large volumes of semi-structured, machine-generated time series data for operational, security, and user behavior insights
  • Full-text search that powers customer applications in their internal networks (content management systems, legal documents) and internet-facing applications such as ecommerce website catalog search and content search

This post focuses on building a simple log analytics pipeline with OpenSearch Serverless.

Solution overview

In the following sections, we walk through the steps to create and access a collection in OpenSearch Serverless, and demonstrate how to configure two different data ingestion pipelines to index data into the collection.

Create a collection

To get started with OpenSearch Serverless, you first create a collection. A collection in OpenSearch Serverless is a logical grouping of one or more indexes that represent an analytics workload.

The following graphic gives a quick navigation for creating a collection. Alternatively, refer to this blog post to learn more about how to create and configure a collection in OpenSearch Serverless.

Access the collection

You can use the AWS Identity and Access Management (IAM) credentials with a secret key and access key ID for your IAM users and roles to access your collection programmatically. Alternatively, you can set up SAML authentication for accessing the OpenSearch Dashboards. Note that SAML authentication is only available to access OpenSearch Dashboards; you require IAM credentials to perform any operations using the AWS Command Line Interface (AWS CLI), API, and OpenSearch clients for indexing and searching data. In this post, we use IAM credentials to access the collections.

Create a data ingestion pipeline

OpenSearch Serverless supports the same ingestion pipelines as the open-source OpenSearch and managed clusters. These clients include applications like Logstash and Amazon Kinesis Data Firehose, and language clients like Java Script, Python, Go, Java, and more. For more details on all the ingestion pipelines and supported clients, refer to ingesting data into OpenSearch Serverless collections.

Using Logstash

The open-source version of Logstash (Logstash OSS) provides a convenient way to use the bulk API to upload data into your collections. OpenSearch Serverless supports the logstash-output-opensearch output plugin, which supports IAM credentials for data access control. In this post, we show how to use the file input plugin to send data from your command line console to an OpenSearch Serverless collection. Complete the following steps:

  1. Download the logstash-oss-with-opensearch-output-plugin file (this example uses the distro for macos-x64; for other distros, refer to the artifacts):
    wget https://artifacts.opensearch.org/logstash/logstash-oss-with-opensearch-output-plugin-8.4.0-macos-x64.tar.gz

  2. Extract the downloaded tarball:
    tar -zxvf logstash-oss-with-opensearch-output-plugin-8.4.0-macos-x64.tar.gz
    cd logstash-8.4.0/

  3. Update the logstash-output-opensearch plugin to the latest version:
    ./bin/logstash-plugin update logstash-output-opensearch

    The OpenSearch output plugin for OpenSearch Serverless uses IAM credentials to authenticate. In this example, we show how to use the file input plugin to read data from a file and ingest into an OpenSearch Serverless collection.

  4. Create a log file with the following sample data and name it sample.log:
    {"deviceId":2823605996,"fleetRegNo":"IRV82MBYQ1","oilLevel":0.92,"milesTravelled":1.105,"totalFuelUsed":0.01,"carrier":"AOS Van Lines","temperature":14,"tripId":6741375582,"originODC":"ODC Las Vegas","originCountry":"United States","originCity":"Las Vegas","originState":"Nevada","originGeo":"36.16,-115.13","destinationODC":"ODC San Jose","destinationCountry":"United States","destinationCity":"San Jose","destinationState":"California","destinationGeo":"37.33,-121.89","speedInMiles":18,"distanceMiles":382.81,"milesToDestination":381.705,"@timestamp":"2022-11-17T17:11:25.855Z","traffic":"heavy","weather_category":"Cloudy","weather":"Cloudy"}
    {"deviceId":2823605996,"fleetRegNo":"IRV82MBYQ1","oilLevel":0.92,"milesTravelled":1.105,"totalFuelUsed":0.01,"carrier":"AOS Van Lines","temperature":14,"tripId":6741375582,"originODC":"ODC Las Vegas","originCountry":"United States","originCity":"Las Vegas","originState":"Nevada","originGeo":"36.16,-115.13","destinationODC":"ODC San Jose","destinationCountry":"United States","destinationCity":"San Jose","destinationState":"California","destinationGeo":"37.33,-121.89","speedInMiles":18,"distanceMiles":382.81,"milesToDestination":381.705,"@timestamp":"2022-11-17T17:11:26.155Z","traffic":"heavy","weather_category":"Cloudy","weather":"Heavy Fog"}
    {"deviceId":2823605996,"fleetRegNo":"IRV82MBYQ1","oilLevel":0.92,"milesTravelled":1.105,"totalFuelUsed":0.01,"carrier":"AOS Van Lines","temperature":14,"tripId":6741375582,"originODC":"ODC Las Vegas","originCountry":"United States","originCity":"Las Vegas","originState":"Nevada","originGeo":"36.16,-115.13","destinationODC":"ODC San Jose","destinationCountry":"United States","destinationCity":"San Jose","destinationState":"California","destinationGeo":"37.33,-121.89","speedInMiles":18,"distanceMiles":382.81,"milesToDestination":381.705,"@timestamp":"2022-11-17T17:11:26.255Z","traffic":"heavy","weather_category":"Cloudy","weather":"Cloudy"}
    {"deviceId":2823605996,"fleetRegNo":"IRV82MBYQ1","oilLevel":0.92,"milesTravelled":1.105,"totalFuelUsed":0.01,"carrier":"AOS Van Lines","temperature":14,"tripId":6741375582,"originODC":"ODC Las Vegas","originCountry":"United States","originCity":"Las Vegas","originState":"Nevada","originGeo":"36.16,-115.13","destinationODC":"ODC San Jose","destinationCountry":"United States","destinationCity":"San Jose","destinationState":"California","destinationGeo":"37.33,-121.89","speedInMiles":18,"distanceMiles":382.81,"milesToDestination":381.705,"@timestamp":"2022-11-17T17:11:26.556Z","traffic":"heavy","weather_category":"Cloudy","weather":"Heavy Fog"}
    {"deviceId":2823605996,"fleetRegNo":"IRV82MBYQ1","oilLevel":0.92,"milesTravelled":1.105,"totalFuelUsed":0.01,"carrier":"AOS Van Lines","temperature":14,"tripId":6741375582,"originODC":"ODC Las Vegas","originCountry":"United States","originCity":"Las Vegas","originState":"Nevada","originGeo":"36.16,-115.13","destinationODC":"ODC San Jose","destinationCountry":"United States","destinationCity":"San Jose","destinationState":"California","destinationGeo":"37.33,-121.89","speedInMiles":18,"distanceMiles":382.81,"milesToDestination":381.705,"@timestamp":"2022-11-17T17:11:26.756Z","traffic":"heavy","weather_category":"Cloudy","weather":"Cloudy"}

  5. Create a new file and add the following content, and save the file as logstash-output-opensearch.conf after providing the information about your file path, host, Region, access key, and secret access key:
    input {
       file {
         path => "<path/to/your/sample.log>"
         start_position => "beginning"
       }
    }
    output {
        opensearch {
            ecs_compatibility => disabled
            index => "logstash-sample"
            hosts => "<HOST>:443"
            auth_type => {
                type => 'aws_iam'
                aws_access_key_id => '<AWS_ACCESS_KEY_ID>'
                aws_secret_access_key => '<AWS_SECRET_ACCESS_KEY>'
                region => '<REGION>'
                service_name => 'aoss'
                }
            legacy_template => false
            default_server_major_version => 2
        }
    }

  6. Use the following command to start Logstash with the config file created in the previous step. This creates an index called logstash-sample and ingests the document added under the sample.log file:
    ./bin/logstash -f <path/to/your/config/file>

  7. Search using OpenSearch Dashboards by running the following query:
    GET logstash-sample/_search
    {
      "query": {
        "match_all": {}
      },
      "track_total_hits" : true
    }

In this step, you used a file input plugin from Logstash to send data to OpenSearch Serverless. You can replace the input plugin with any other plugin supported by Logstash, such as Amazon Simple Storage Service (Amazon S3), stdin, tcp, or others, to send data to the OpenSearch Serverless collection.

Using a Python client

OpenSearch provides high-level clients for several popular programming languages, which you can use to integrate with your application. With OpenSearch Serverless, you can continue to use your existing OpenSearch client to load and query your data in collections.

In this section, we show how to use the opensearch-py client for Python to establish a secure connection with your OpenSearch Serverless collection, create an index, send sample logs, and analyze those log data using OpenSearch Dashboards. In this example, we use a sample event generated from fleets carrying goods and packages. This data contains pertinent fields such as source, destination, weather, speed, and traffic. The following is a sample record:

"_source" : {
    "deviceId" : 2823605996,
    "fleetRegNo" : "IRV82MBYQ1",
    "carrier" : "AOS Van Lines",
    "temperature" : 14,
    "tripId" : 6741375582,
    "originODC" : "ODC Las Vegas",
    "originCountry" : "United States",
    "originCity" : "Las Vegas",
    "destinationCity" : "San Jose",
    "@timestamp" : "2022-11-17T17:11:25.855Z",
    "traffic" : "heavy",
    "weather" : "Cloudy"
    ...
    ...
}

To set up the Python client for OpenSearch, you must have the following prerequisites:

  • Python3 installed on your local machine or the server from where you are running this code
  • Package Installer for Python (PIP) installed
  • The AWS CLI configured; we use it to store the secret key and access key for credentials

Complete the following steps to set up the Python client:

  1. Add the OpenSearch Python client to your project and use Python’s virtual environment to set up the required packages:
    mkdir python-sample
    cd python-sample
    python3 -m venv .env
    source .env/bin/activate
    .env/bin/python3 -m pip install opensearch-py
    .env/bin/python3 -m pip install requests_aws4auth
    .env/bin/python3 -m pip install boto3
    .env/bin/python3 -m pip install geopy

  2. Save your frequently used configuration settings and credentials in files that are maintained by the AWS CLI (see Quick configuration with aws configure) by using the following commands and providing your access key, secret key, and Region:
    aws configure

  3. The following sample code uses the opensearch-py client for Python to establish a secure connection to the specified OpenSearch Serverless collection and index a sample document to index time series. You must provide values for region and host. Note that you must use aoss as the service name for OpenSearch Service. Copy the code and save in a file as sample_python.py:
    from opensearchpy import OpenSearch, RequestsHttpConnection
    from requests_aws4auth import AWS4Auth
    import boto3
    
    host = '<host>' # OpenSearch Serverless collection endpoint
    region = '<region>' # e.g. us-west-2
    
    service = 'aoss'
    credentials = boto3.Session().get_credentials()
    awsauth = AWS4Auth(credentials.access_key, credentials.secret_key, region, service,
    session_token=credentials.token)
    
    # Create an OpenSearch client
    client = OpenSearch(
        hosts = [{'host': host, 'port': 443}],
        http_auth = awsauth,
        use_ssl = True,
        verify_certs = True,
        connection_class = RequestsHttpConnection
    )
    # Specify index name
    index_name = 'octank-iot-logs-2022-11-19'
    
    # Prepare a document to index 
    document = {
        "deviceId" : 2823605996,
        "fleetRegNo" : "IRV82MBYQ1",
        "carrier" : "AOS Van Lines",
        "temperature" : 14,
        "tripId" : 6741375582,
        "originODC" : "ODC Las Vegas",
        "originCountry" : "United States",
        "originCity" : "Las Vegas",
        "destinationCity" : "San Jose",
        "@timestamp" : "2022-11-19T17:11:25.855Z",
        "traffic" : "heavy",
        "weather" : "Cloudy"
    }
    
    # Index Documents
    response = client.index(
        index = index_name,
        body = document
    )
    
    print('\n Document indexed with response:')
    print(response)
    
    
    # Search for the Documents
    q = 'heavy'
    query = {
        'size': 5,
            'query': {
            'multi_match': {
            'query': q,
            'fields': ['traffic']
            }
        }
    }
    
    response = client.search(
    body = query,
    index = index_name
    )
    print('\nSearch results:')
    print(response)

  4. Run the sample code:
    python3 sample_python.py

  5. On the OpenSearch Service console, select your collection.
  6. On OpenSearch Dashboards, choose Dev Tools.
  7. Run the following search query to retrieve documents:
    GET octank-iot-logs-*/_search
    {
      "query": {
        "match_all": {}
      }
    }

After you have ingested the data, you can use OpenSearch Dashboards to visualize your data. In the following example, we analyze data visually to gain insights on various dimensions such as average fuel consumed by a specific fleet, traffic conditions, distance traveled, and average mileage by the fleet.

Conclusion

In this post, you created a log analytics pipeline using OpenSearch Serverless, a new serverless option for OpenSearch Service. With OpenSearch Serverless, you can focus on building your application without having to worry about provisioning, tuning, and scaling the underlying infrastructure. OpenSearch Serverless supports the same ingestion pipelines and high-level clients as the open-source OpenSearch project. You can easily get started using the familiar OpenSearch indexing and query APIs to load and search your data and use OpenSearch Dashboards to visualize that data.

Stay tuned for a series of posts focusing on the various options available for you to build effective log analytics and search applications. Get hands-on with OpenSearch Serverless by taking the Getting Started with Amazon OpenSearch Serverless workshop and build a similar log analytics pipeline that was discussed in this post.


About the authors

Prashant Agrawal is a Sr. Search Specialist Solutions Architect with Amazon OpenSearch Service. He works closely with customers to help them migrate their workloads to the cloud and helps existing customers fine-tune their clusters to achieve better performance and save on cost. Before joining AWS, he helped various customers use OpenSearch and Elasticsearch for their search and log analytics use cases. When not working, you can find him traveling and exploring new places. In short, he likes doing Eat → Travel → Repeat.

Pavani Baddepudi is a senior product manager working in search services at AWS. Her interests include distributed systems, networking, and security.

Introducing new AWS Serverless digital learning badges

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/introducing-new-aws-serverless-digital-learning-badges/

This post is written by Josh Kahn, Tech Leader, Serverless.

Today, we are excited to announce an all-new way to demonstrate your AWS Serverless knowledge and skills: a verifiable, digital badge. The new digital badge is aligned with our Serverless Learning Plan now available in AWS Skill Builder.

You can earn the digital badge by scoring at least 80 percent on the assessment associated with the Learning Plan. The badge proves your knowledge and skills for AWS Lambda, Amazon API Gateway, and designing serverless applications. You can celebrate your achievement on your resume, social media, and AWS re:Post with the verifiable badge distributed and managed by Credly. The badge includes metadata to verify the issuer and skills demonstrated by the holder. The Serverless Learning Plan and digital badge assessment are now available, for free.

Ready to get started or want to jump immediately to the assessment? Start here. Continue reading to learn more about the details of AWS Skill Builder and our Serverless Learning Plan.

Serverless Digital Learning Badge

The Serverless Learning Plan

Our Serverless Learning Plan has been designed to help you get started building with Serverless technology. AWS experts designed the content to provide a clear learning path to help you develop the skills you need quickly.

The Learning Plan starts with an introduction to the “Serverless Mindset” and introduces key concepts to help you design architectures and applications. It discusses how to best take advantage of the event-driven orientation of serverless computing.

Next, the course “AWS Lambda Foundations” covers the fundamentals of AWS Lambda, an event-driven compute service that lets you run code without provisioning or managing servers. You’ll learn foundational concepts, including how Lambda works, security and permission models, and best practices for writing Lambda functions.

The Learning Plan also includes four courses that span the lifecycle of building Lambda-based applications. In “Architecting Serverless Applications,” you learn about common architectures and patterns for serverless applications. We explore how to build microservices, data processing workloads, Alexa skills, mobile backends, and automate tasks in your AWS account. The course also discusses the trade-offs in selecting from the various compute options available to you.

The “Scaling Serverless Architectures” course discusses concepts such as Lambda concurrency and how Lambda-based applications scale. We briefly explore optimization opportunities for Lambda functions and trade-offs. While this course is not a deep dive in optimization across all supported runtimes, it offers a starting point.

In “Security and Observability for Serverless Applications,” you’ll learn how to use services such as AWS CloudTrail, AWS Config, and AWS X-Ray in concert with Lambda-based applications. We also discuss the built-in logging to Amazon CloudWatch and considerations. This course also touches on how the Lambda service creates isolation and a security boundary between functions.

There are a number of popular options for deploying and managing serverless applications. In “Deploying Serverless Applications,” we explore the AWS Serverless Application Model (AWS SAM) and the AWS suite of developer tools. You’ll learn best practices for deployment, including how to automate deployment using a CI/CD pipeline. This course also covers concepts such as Lambda versions and aliases, Lambda environment variables, and other deployment features.

Serverless is more than Lambda. During the Learning Plan, you also learn how to use Amazon API Gateway to create and deploy serverless APIs. “Amazon API Gateway for Serverless Applications” discusses REST and WebSocket options available from API Gateway and how to integrate with Lambda and other backends. The course also discusses the rich set of API Gateway features available, including caching, various authorization modes, usage plans, API keys, and deployment stages.

To complete the Learning Plan, we also provide an introduction to event-driven architectures built using services such as AWS Step Functions and Amazon Simple Queue Service (SQS). This course compliments the “Serverless Mindset” course to help you think about how asynchronous processing can improve the resiliency and scalability of your serverless applications.

All courses are available in a variety of languages.

After completing the Learning Plan, take the online assessment and score over 80 percent to earn the digital badge. Our badge assessments are linked to curriculum standards and have been developed by field subject matter experts (SMEs) and content/curriculum SMEs. If you are already familiar with AWS Serverless, you can also jump right to the assessment. If you don’t pass, you’ll be guided on how to fill knowledge gaps and can retake the assessment after 24 hours.

We’re also working to add more courses on topics, such as Amazon EventBridge, and more extensive course work on event-driven architectures next year. Stay tuned.

Our Learning Plan has been designed for you to move at your own pace, from wherever you are. It’s a great opportunity to build new skills or refresh your knowledge. Employers seeking to build knowledge in Serverless can also use the Learning Plan and digital badge to build critical knowledge in the space.

AWS Skill Builder

Beyond our recommended Serverless curriculum, Skill Builder offers a bevy of digital courses developed for different roles (e.g., developer, architect, data engineer) and domains (e.g., storage, databases). Skill Builder offers free learning content as well as subscription plans for individuals and teams. Skill Builder is a great way to advance your skills in areas that often touch serverless applications, including security, observability / monitoring, and DevOps.

We encourage you to check out these other expert-designed courses to help advance your knowledge of AWS. Subscription plans include hands-on labs and certification practice exams. The free content includes over 500 courses and learning plans, all available on-demand so that you can learn at your own pace.

Dive deeper with the AWS Serverless Ramp-up Guide

If you want to dive deeper after completing the AWS Serverless Learning Plan, download the AWS Ramp-Up Guide for Serverless. The guide includes a listing of courses, hands-on workshops, classroom training, and other resources to enrich your serverless knowledge.

Think of the Ramp-Up Guide as a menu of options. Pick and choose the topics that are most interesting to you and move at your own pace. We’ve included digital courses, reading, videos, and workshops to help you learn however is most effective for you.

We’re working to continually update the Ramp-up Guide so that you can easily find up-to-date content to deepen your skills. Check back for updates.

Conclusion

We’re excited to share the newly updated Serverless Learning Plan and all-new digital badge with you. To our knowledge, this is one of the first ways (if not the first) that Serverless builders can verifiably demonstrate their knowledge to the community and employers. Our team of SMEs across AWS Serverless and Training & Certification are excited to hear your feedback on the Learning Plan as well as where you would like to see us develop training next.

The AWS Serverless Learning Plan and digital badge are available now. All courses are available on-demand. Both the learning plan courses and the assessment are free for everyone.

Share your accomplishment by posting on social media with the hashtag #AWSTraining! Get started today at https://aws.amazon.com/training/learn-about/serverless/.

For more serverless learning resources, visit Serverless Land.

Reducing Java cold starts on AWS Lambda functions with SnapStart

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/reducing-java-cold-starts-on-aws-lambda-functions-with-snapstart/

Written by Mark Sailes, Senior Serverless Solutions Architect, AWS.

At AWS re:Invent 2022, AWS announced SnapStart for AWS Lambda functions running on Java Corretto 11. This feature enables customers to achieve up to 10x faster function startup performance for Java functions, at no additional cost, and typically with minimal or no code changes.

Overview

Today, for Lambda’s function invocations, the largest contributor to startup latency is the time spent initializing a function. This includes loading the function’s code and initializing dependencies. For interactive workloads that are sensitive to start-up latencies, this can cause suboptimal end user experience.

To address this challenge, customers either provision resources ahead of time, or spend effort building relatively complex performance optimizations, such as compiling with GraalVM native-image. Although these workarounds help reduce the startup latency, users must spend time on some heavy lifting instead of focusing on delivering business value. SnapStart addresses this concern directly for Java-based Lambda functions.

How SnapStart works

With SnapStart, when a customer publishes a function version, the Lambda service initializes the function’s code. It takes an encrypted snapshot of the initialized execution environment, and persists the snapshot in a tiered cache for low latency access.

When the function is first invoked and then scaled, Lambda resumes the execution environment from the persisted snapshot instead of initializing from scratch. This results in a lower startup latency.

Lambda function lifecycle

Lambda function lifecycle

A function version activated with SnapStart transitions to an inactive state if it remains idle for 14 days, after which Lambda deletes the snapshot. When you try to invoke a function version that is inactive, the invocation fails. Lambda sends a SnapStartNotReadyException and begins initializing a new snapshot in the background, during which the function version remains in Pending state. Wait until the function reaches the Active state, and then invoke it again. To learn more about this process and the function states, read the documentation.

Using SnapStart

Application frameworks such as Spring give developers an enormous productivity gain by reducing the amount of boilerplate code they write to accomplish common tasks. When first created, frameworks didn’t have to consider startup time because they run on application servers, which run for long periods of time. The startup time is minimal compared to the running duration. You often only restart them when there is an application version change.

If the functionality that these frameworks bring is implemented at runtime, then they often contribute to latency in startup time. SnapStart allows you to use frameworks like Spring and not compromise tail latency.

To demonstrate SnapStart, I use a sample application that saves records into Amazon DynamoDB. This Spring Boot application (TODO Link) uses a REST controller to handle CRUD requests. This sample includes infrastructure as code to deploy the application using the AWS Serverless Application Model (AWS SAM). You must install the AWS SAM CLI to deploy this example.

To deploy:

  1. Clone the git repository and change to project directory:
    git clone https://github.com/aws-samples/serverless-patterns.git
    cd serverless-patterns/apigw-lambda-snapstart
  2. Use the AWS SAM CLI to build the application:
    sam build
  3. Use the AWS SAM CLI to deploy the resources to your AWS account:
    sam deploy -g

This project deploys with SnapStart already enabled. To enable or disable this functionality in the AWS Management Console:

  1. Navigate to your Lambda function.
  2. Select the Configuration tab.
  3. Choose Edit and change the SnapStart attribute to PublishedVersions.
  4. Choose Save.

    Lambda Console confoguration

    Lambda Console confoguration

  5. Select the Versions tab and choose Publish new.
  6. Choose Publish.

Once you’ve enabled SnapStart, Lambda publishes all subsequent versions with snapshots. The time to run your publish version depends on your init code. You can run init up to 15 minutes with this feature.

Considerations

Stale credentials

Using SnapStart and restoring from a snapshot often changes how you create functions. With on-demand functions, you might access one time data in the init phase, and then reuse it during future invokes. If this data is ephemeral, a database password for example, then there might be a time between fetching the secret and using it, that the password has changed leading to an error. You must write code to handle this error case.

With SnapStart, if you follow the same approach, your database password is persisted in an encrypted snapshot. All future execution environments have the same state. This can be days, weeks, or longer after the snapshot is taken. This makes it more likely that your function has the incorrect password stored. To improve this, you could move the functionality to fetch the password to the post-snapshot hook. With each approach, it is important to understand your application’s needs and handle errors when they occur.

Demo application architecture

Demo application architecture

A second challenge in sharing the initial state is with randomness and uniqueness. If random seeds are stored in the snapshot during the initialization phase, then it may cause random numbers to be predictable.

Cryptography

AWS has changed the managed runtime to help customers handle the effects of uniqueness and randomness when restoring functions.

Lambda has already incorporated updates to Amazon Linux 2 and one of the commonly used cryptographic libraries, OpenSSL (1.0.2), to make them resilient to snapshot operations. AWS has also validated that Java runtime’s built-in RNG java.security.SecureRandom maintains uniqueness when resuming from a snapshot.

Software that always gets random numbers from the operating system (for example, from /dev/random or /dev/urandom) is already resilient to snapshot operations. It does not need updates to restore uniqueness. However, customers who prefer to implement uniqueness using custom code for their Lambda functions must verify that their code restores uniqueness when using SnapStart.

For more details, read Starting up faster with AWS Lambda SnapStart and refer to Lambda documentation on SnapStart uniqueness.

Runtime hooks

These pre- and post-hooks give developers a way to react to the snapshotting process.

For example, a function that must always preload large amounts of data from Amazon S3 should do this before Lambda takes the snapshot. This embeds the data in the snapshot so that it does not need fetching repeatedly. However, in some cases, you may not want to keep ephemeral data. A password to a database may be rotated frequently and cause unnecessary errors. I discuss this in greater detail in a later section.

The Java managed runtime uses the open-source Coordinated Restore at Checkpoint (CRaC) project to provide hook support. The managed Java runtime contains a customized CRaC context implementation that calls your Lambda function’s runtime hooks before completing snapshot creation and after restoring the execution environment from a snapshot.

The following function example shows how you can create a function handler with runtime hooks. The handler implements the CRaC Resource and the Lambda RequestHandler interface.

...
import org.crac.Resource;
import org.crac.Core;
...

public class HelloHandler implements RequestHandler<String, String>, Resource {

    public HelloHandler() {
        Core.getGlobalContext().register(this);
    }

    public String handleRequest(String name, Context context) throws IOException {
        System.out.println("Handler execution");
        return "Hello " + name;
    }

    @Override
    public void beforeCheckpoint(org.crac.Context<? extends Resource> context) throws Exception {
        System.out.println("Before Checkpoint");
    }

    @Override
    public void afterRestore(org.crac.Context<? extends Resource> context) throws Exception {
        System.out.println("After Restore");
    }
}

For the classes required to write runtime hooks, add the following dependency to your project:

Maven

<dependency>
  <groupId>io.github.crac</groupId>
  <artifactId>org-crac</artifactId>
  <version>0.1.3</version>
</dependency>

Gradle

implementation 'io.github.crac:org-crac:0.1.3'

Priming

SnapStart and runtime hooks give you new ways to build your Lambda functions for low startup latency. You can use the pre-snapshot hook to make your Java application as ready as possible for the first invoke. Do as much as possible within your function before the snapshot is taken. This is called priming.

When you upload your zip file of Java code to Lambda, the zip contains .class files of bytecode. This can be run on any machine with a JVM. When the JVM executes your bytecode, it is initially interpreted, then compiled into native machine code. This compilation stage is relatively CPU intensive and happens just in time (JIT Compiler).

You can use the before snapshot hook to run code paths before the snapshot is taken. The JVM compiles these code paths and the optimization is kept for future restores. For example, if you have a function that integrates with DynamoDB, you can make a read operation in your before snapshot hook.

This means that your function code, the AWS SDK for Java, and any other libraries used in that action are compiled and kept within the snapshot. The JVM then won’t need to compile this code when your function is invoked, meaning your latency is less the first time an execution environment is invoked.

Priming requires that you understand your application code and the consequences of executing it. The sample application includes a before snapshot hook, which primes the application by making a read operation from DynamoDB. (TODO Link)

Metrics

The following chart reflects invoking the sample application Lambda function 100 times per second for 10 minutes. This test is based on this function, both with and without SnapStart.


p50 p99.9
On-demand 7.87ms 5,114ms
SnapStart 7.87ms 488ms

Conclusion

This blog shows how SnapStart reduces startup (cold-start) latencies times for Java-based Lambda functions. You can configure SnapStart using AWS SDK, AWS CloudFormation, AWS SAM, and CDK.

To learn more, see Configuring function options in the AWS documentation. This functionality may require some minimal code changes. In most cases, the existing code is already compatible with SnapStart. You can now bring your latency-sensitive Java-based workloads to Lambda and run with improved tail latencies.

This feature allows developers to use the on-demand model in Lambda with low-latency response times, without incurring extra cost. To read more about how to use SnapStart with partner frameworks, find out more from Quarkus and Micronaut. To read more about this and other features, visit Serverless Land.