Tag Archives: Uncategorized

Friday Squid Blogging: Squid Brand Fish Sauce

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/friday-squid-blogging-squid-brand-fish-sauce.html

Squid Brand is a Thai company that makes fish sauce:

It is part of Squid Brand’s range of “personalized healthy fish sauces” that cater to different consumer groups, which include the Mild Fish Sauce for Kids and Mild Fish Sauce for Silver Ages.

It also has a Vegan Fish Sauce.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Bots Are Better than Humans at Solving CAPTCHAs

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/bots-are-better-than-humans-at-solving-captchas.html

Interesting research: “An Empirical Study & Evaluation of Modern CAPTCHAs“:

Abstract: For nearly two decades, CAPTCHAS have been widely used as a means of protection against bots. Throughout the years, as their use grew, techniques to defeat or bypass CAPTCHAS have continued to improve. Meanwhile, CAPTCHAS have also evolved in terms of sophistication and diversity, becoming increasingly difficult to solve for both bots (machines) and humans. Given this long-standing and still-ongoing arms race, it is critical to investigate how long it takes legitimate users to solve modern CAPTCHAS, and how they are perceived by those users.

In this work, we explore CAPTCHAS in the wild by evaluating users’ solving performance and perceptions of unmodified currently-deployed CAPTCHAS. We obtain this data through manual inspection of popular websites and user studies in which 1, 400 participants collectively solved 14, 000 CAPTCHAS. Results show significant differences between the most popular types of CAPTCHAS: surprisingly, solving time and user perception are not always correlated. We performed a comparative study to investigate the effect of experimental context ­ specifically the difference between solving CAPTCHAS directly versus solving them as part of a more natural task, such as account creation. Whilst there were several potential confounding factors, our results show that experimental context could have an impact on this task, and must be taken into account in future CAPTCHA studies. Finally, we investigate CAPTCHA-induced user task abandonment by analyzing participants who start and do not complete the task.

Slashdot thread.

And let’s all rewatch this great ad from 2022.

How to add notifications and manual approval to an AWS CDK Pipeline

Post Syndicated from Jehu Gray original https://aws.amazon.com/blogs/devops/how-to-add-notifications-and-manual-approval-to-an-aws-cdk-pipeline/

A deployment pipeline typically comprises several stages such as dev, test, and prod, which ensure that changes undergo testing before reaching the production environment. To improve the reliability and stability of release processes, DevOps teams must review Infrastructure as Code (IaC) changes before applying them in production. As a result, implementing a mechanism for notification and manual approval that grants stakeholders improved access to changes in their release pipelines has become a popular practice for DevOps teams.

Notifications keep development teams and stakeholders informed in real-time about updates and changes to deployment status within release pipelines. Manual approvals establish thresholds for transitioning a change from one stage to the next in the pipeline. They also act as a guardrail to mitigate risks arising from errors and rework because of faulty deployments.

Please note that manual approvals, as described in this post, are not a replacement for the use of automation. Instead, they complement automated checks within the release pipeline.

In this blog post, we describe how to set up notifications and add a manual approval stage to AWS Cloud Development Kit (AWS CDK) Pipeline.

Concepts

CDK Pipeline

CDK Pipelines is a construct library for painless continuous delivery of CDK applications. CDK Pipelines can automatically build, test, and deploy changes to CDK resources. CDK Pipelines are self-mutating which means as application stages or stacks are added, the pipeline automatically reconfigures itself to deploy those new stages or stacks. Pipelines need only be manually deployed once, afterwards, the pipeline keeps itself up to date from the source code repository by pulling the changes pushed to the repository.

Notifications

Adding notifications to a pipeline provides visibility to changes made to the environment by utilizing the NotificationRule construct. You can also use this rule to notify pipeline users of important changes, such as when a pipeline starts execution. Notification rules specify both the events and the targets, such as Amazon Simple Notification Service (Amazon SNS) topic or AWS Chatbot clients configured for Slack which represents the nominated recipients of the notifications. An SNS topic is a logical access point that acts as a communication channel while Chatbot is an AWS service that enables DevOps and software development teams to use messaging program chat rooms to monitor and respond to operational events.

Manual Approval

In a CDK pipeline, you can incorporate an approval action at a specific stage, where the pipeline should pause, allowing a team member or designated reviewer to manually approve or reject the action. When an approval action is ready for review, a notification is sent out to alert the relevant parties. This combination of notifications and approvals ensures timely and efficient decision-making regarding crucial actions within the pipeline.

Solution Overview

The solution explains a simple web service that is comprised of an AWS Lambda function that returns a static web page served by Amazon API Gateway. Since Continuous Deployment and Continuous Integration (CI/CD) are important components to most web projects, the team implements a CDK Pipeline for their web project.

There are two important stages in this CDK pipeline; the Pre-production stage for testing and the Production stage, which contains the end product for users.

The flow of the CI/CD process to update the website starts when a developer pushes a change to the repository using their Integrated Development Environment (IDE). An Amazon CloudWatch event triggers the CDK Pipeline. Once the changes reach the pre-production stage for testing, the CI/CD process halts. This is because a manual approval gate is between the pre-production and production stages. So, it becomes a stakeholder’s responsibility to review the changes in the pre-production stage before approving them for production. The pipeline includes an SNS notification that notifies the stakeholder whenever the pipeline requires manual approval.

After approving the changes, the CI/CD process proceeds to the production stage and the updated version of the website becomes available to the end user. If the approver rejects the changes, the process ends at the pre-production stage with no impact to the end user.

The following diagram illustrates the solution architecture.


This diagram shows the CDK pipeline process in the solution and how applications or updates are deployed using AWS Lambda Function to end users.

Figure 1. This image shows the CDK pipeline process in our solution and how applications or updates are deployed using AWS Lambda Function to end users.

Prerequisites

For this walkthrough, you should have the following prerequisites:

Add notification to the pipeline

In this tutorial, perform the following steps:

  • Add the import statements for AWS CodeStar notifications and SNS to the import section of the pipeline stack py
import aws_cdk.aws_codestarnotifications as notifications
import aws_cdk.pipelines as pipelines
import aws_cdk.aws_sns as sns
import aws_cdk.aws_sns_subscriptions as subs
  • Ensure the pipeline is built by calling the ‘build pipeline’ function.

pipeline.build_pipeline()

  • Create an SNS topic.

topic = sns.Topic(self, "MyTopic1")

  • Add a subscription to the topic. This specifies where the notifications are sent (Add the stakeholders’ email here).

topic.add_subscription(subs.EmailSubscription("[email protected]"))

  • Define a rule. This contains the source for notifications, the event trigger, and the target .

rule = notifications.NotificationRule(self, "NotificationRule", )

  • Assign the source the value pipeline.pipeline The first pipeline is the name of the CDK pipeline(variable) and the .pipeline is to show it is a pipeline(function).

source=pipeline.pipeline,

  • Define the events to be monitored. Specify notifications for when the pipeline starts, when it fails, when the execution succeeds, and finally when manual approval is needed.
events=["codepipeline-pipeline-pipeline-execution-started", "codepipeline-pipeline-pipeline-execution-failed","codepipeline-pipeline-pipeline-execution-succeeded", 
"codepipeline-pipeline-manual-approval-needed"],
  • For the complete list of supported event types for pipelines, see here
  • Finally, add the target. The target here is the topic created previously.

targets=[topic]

The combination of all the steps becomes:

pipeline.build_pipeline()
topic = sns.Topic(self, "MyTopic1")
topic.add_subscription(subs.EmailSubscription("[email protected]"))
rule = notifications.NotificationRule(self, "NotificationRule",
source=pipeline.pipeline,
events=["codepipeline-pipeline-pipeline-execution-started", "codepipeline-pipeline-pipeline-execution-failed","codepipeline-pipeline-pipeline-execution-succeeded", 
"codepipeline-pipeline-manual-approval-needed"],
targets=[topic]
)

Adding Manual Approval

  • Add the ManualApprovalStep import to the aws_cdk.pipelines import statement.
from aws_cdk.pipelines import (
CodePipeline,
CodePipelineSource,
ShellStep,
ManualApprovalStep
)
  • Add the ManualApprovalStep to the production stage. The code must be added to the add_stage() function.
 prod = WorkshopPipelineStage(self, "Prod")
        prod_stage = pipeline.add_stage(prod,
            pre = [ManualApprovalStep('PromoteToProduction')])

When a stage is added to a pipeline, you can specify the pre and post steps, which are arbitrary steps that run before or after the contents of the stage. You can use them to add validations like manual or automated gates to the pipeline. It is recommended to put manual approval gates in the set of pre steps, and automated approval gates in the set of post steps. So, the manual approval action is added as a pre step that runs after the pre-production stage and before the production stage .

  • The final version of the pipeline_stack.py becomes:
from constructs import Construct
import aws_cdk as cdk
import aws_cdk.aws_codestarnotifications as notifications
import aws_cdk.aws_sns as sns
import aws_cdk.aws_sns_subscriptions as subs
from aws_cdk import (
    Stack,
    aws_codecommit as codecommit,
    aws_codepipeline as codepipeline,
    pipelines as pipelines,
    aws_codepipeline_actions as cpactions,
    
)
from aws_cdk.pipelines import (
    CodePipeline,
    CodePipelineSource,
    ShellStep,
    ManualApprovalStep
)


class WorkshopPipelineStack(cdk.Stack):
    def __init__(self, scope: Construct, id: str, **kwargs) -> None:
        super().__init__(scope, id, **kwargs)
        
        # Creates a CodeCommit repository called 'WorkshopRepo'
        repo = codecommit.Repository(
            self, "WorkshopRepo", repository_name="WorkshopRepo",
            
        )
        
        #Create the Cdk pipeline
        pipeline = pipelines.CodePipeline(
            self,
            "Pipeline",
            
            synth=pipelines.ShellStep(
                "Synth",
                input=pipelines.CodePipelineSource.code_commit(repo, "main"),
                commands=[
                    "npm install -g aws-cdk",  # Installs the cdk cli on Codebuild
                    "pip install -r requirements.txt",  # Instructs Codebuild to install required packages
                    "npx cdk synth",
                ]
                
            ),
        )

        
         # Create the Pre-Prod Stage and its API endpoint
        deploy = WorkshopPipelineStage(self, "Pre-Prod")
        deploy_stage = pipeline.add_stage(deploy)
    
        deploy_stage.add_post(
            
            pipelines.ShellStep(
                "TestViewerEndpoint",
                env_from_cfn_outputs={
                    "ENDPOINT_URL": deploy.hc_viewer_url
                },
                commands=["curl -Ssf $ENDPOINT_URL"],
            )
    
        
        )
        deploy_stage.add_post(
            pipelines.ShellStep(
                "TestAPIGatewayEndpoint",
                env_from_cfn_outputs={
                    "ENDPOINT_URL": deploy.hc_endpoint
                },
                commands=[
                    "curl -Ssf $ENDPOINT_URL",
                    "curl -Ssf $ENDPOINT_URL/hello",
                    "curl -Ssf $ENDPOINT_URL/test",
                ],
            )
            
        )
        
        # Create the Prod Stage with the Manual Approval Step
        prod = WorkshopPipelineStage(self, "Prod")
        prod_stage = pipeline.add_stage(prod,
            pre = [ManualApprovalStep('PromoteToProduction')])
        
        prod_stage.add_post(
            
            pipelines.ShellStep(
                "ViewerEndpoint",
                env_from_cfn_outputs={
                    "ENDPOINT_URL": prod.hc_viewer_url
                },
                commands=["curl -Ssf $ENDPOINT_URL"],
                
            )
            
        )
        prod_stage.add_post(
            pipelines.ShellStep(
                "APIGatewayEndpoint",
                env_from_cfn_outputs={
                    "ENDPOINT_URL": prod.hc_endpoint
                },
                commands=[
                    "curl -Ssf $ENDPOINT_URL",
                    "curl -Ssf $ENDPOINT_URL/hello",
                    "curl -Ssf $ENDPOINT_URL/test",
                ],
            )
            
        )
        
        # Create The SNS Notification for the Pipeline
        
        pipeline.build_pipeline()
        
        topic = sns.Topic(self, "MyTopic")
        topic.add_subscription(subs.EmailSubscription("[email protected]"))
        rule = notifications.NotificationRule(self, "NotificationRule",
            source = pipeline.pipeline,
            events = ["codepipeline-pipeline-pipeline-execution-started", "codepipeline-pipeline-pipeline-execution-failed", "codepipeline-pipeline-manual-approval-needed", "codepipeline-pipeline-manual-approval-succeeded"],
            targets=[topic]
            )


When a commit is made with git commit -am "Add manual Approval" and changes are pushed with git push, the pipeline automatically self-mutates to add the new approval stage.

Now when the developer pushes changes to update the build environment or the end user application, the pipeline execution stops at the point where the approval action was added. The pipeline won’t resume unless a manual approval action is taken.

Image showing the CDK pipeline with the added Manual Approval action on the AWS Management Console

Figure 2. This image shows the pipeline with the added Manual Approval action.

Since there is a notification rule that includes the approval action, an email notification is sent with the pipeline information and approval status to the stakeholder(s) subscribed to the SNS topic.

Image showing the SNS email notification sent when the pipeline starts

Figure 3. This image shows the SNS email notification sent when the pipeline starts.

After pushing the updates to the pipeline, the reviewer or stakeholder can use the AWS Management Console to access the pipeline to approve or deny changes based on their assessment of these changes. This process helps eliminate any potential issues or errors and ensures only changes deemed relevant are made.

Image showing the review action on the AWS Management Console that gives the stakeholder the ability to approve or reject any changes.

Figure 4. This image shows the review action that gives the stakeholder the ability to approve or reject any changes. 

If a reviewer rejects the action, or if no approval response is received within seven days of the pipeline stopping for the review action, the pipeline status is “Failed.”

Image showing when a stakeholder rejects the action

Figure 5. This image depicts when a stakeholder rejects the action.

If a reviewer approves the changes, the pipeline continues its execution.

Image showing when a stakeholder approves the action

Figure 6. This image depicts when a stakeholder approves the action.

Considerations

It is important to consider any potential drawbacks before integrating a manual approval process into a CDK pipeline. one such consideration is its implementation may delay the delivery of updates to end users. An example of this is business hours limitation. The pipeline process might be constrained by the availability of stakeholders during business hours. This can result in delays if changes are made outside regular working hours and require approval when stakeholders are not immediately accessible.

Clean up

To avoid incurring future charges, delete the resources. Use cdk destroy via the command line to delete the created stack.

Conclusion

Adding notifications and manual approval to CDK Pipelines provides better visibility and control over the changes made to the pipeline environment. These features ideally complement the existing automated checks to ensure that all updates are reviewed before deployment. This reduces the risk of potential issues arising from bugs or errors. The ability to approve or deny changes through the AWS Management Console makes the review process simple and straightforward. Additionally, SNS notifications keep stakeholders updated on the status of the pipeline, ensuring a smooth and seamless deployment process.

Jehu Gray

Jehu Gray is an Enterprise Solutions Architect at Amazon Web Services where he helps customers design solutions that fits their needs. He enjoys exploring whats possible with IaC such as CDK.

Abiola Olanrewaju

Abiola Olanrewaju is an Enterprise Solutions Architect at Amazon Web Services where he helps customers design and implement scalable solutions that drive business outcomes. He has a keen interest in Data Analytics, Security and Automation.

Serge Poueme

Serge Poueme is a Solutions Architect on the AWS for Games Team. He started his career as a software development engineer and enjoys building new products. At AWS, Serge focuses on improving Builders Experience for game developers and optimize servers hosting using Containers. When he is not working he enjoys playing Far Cry or Fifa on his XBOX

Detecting “Violations of Social Norms” in Text with AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/detecting-violations-of-social-norms-in-text-with-ai.html

Researchers are trying to use AI to detect “social norms violations.” Feels a little sketchy right now, but this is the sort of thing that AIs will get better at. (Like all of these systems, anything but a very low false positive rate makes the detection useless in practice.)

News article.

UK Electoral Commission Hacked

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/uk-electoral-commission-hacked.html

The UK Electoral Commission discovered last year that it was hacked the year before. That’s fourteen months between the hack and the discovery. It doesn’t know who was behind the hack.

We worked with external security experts and the National Cyber Security Centre to investigate and secure our systems.

If the hack was by a major government, the odds are really low that it has resecured its systems—unless it burned the network to the ground and rebuilt it from scratch (which seems unlikely).

Zoom Can Spy on Your Calls and Use the Conversation to Train AI, But Says That It Won’t

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/zoom-can-spy-on-your-calls-and-use-the-conversation-to-train-ai-but-says-that-it-wont.html

This is why we need regulation:

Zoom updated its Terms of Service in March, spelling out that the company reserves the right to train AI on user data with no mention of a way to opt out. On Monday, the company said in a blog post that there’s no need to worry about that. Zoom execs swear the company won’t actually train its AI on your video calls without permission, even though the Terms of Service still say it can.

Of course, these are Terms of Service. They can change at any time. Zoom can renege on its promise at any time. There are no rules, only the whims of the company as it tries to maximize its profits.

It’s a stupid way to run a technological revolution. We should not have to rely on the benevolence of for-profit corporations to protect our rights. It’s not their job, and it shouldn’t be.

Implementing automatic drift detection in CDK Pipelines using Amazon EventBridge

Post Syndicated from DAMODAR SHENVI WAGLE original https://aws.amazon.com/blogs/devops/implementing-automatic-drift-detection-in-cdk-pipelines-using-amazon-eventbridge/

The AWS Cloud Development Kit (AWS CDK) is a popular open source toolkit that allows developers to create their cloud infrastructure using high level programming languages. AWS CDK comes bundled with a construct called CDK Pipelines that makes it easy to set up continuous integration, delivery, and deployment with AWS CodePipeline. The CDK Pipelines construct does all the heavy lifting, such as setting up appropriate AWS IAM roles for deployment across regions and accounts, Amazon Simple Storage Service (Amazon S3) buckets to store build artifacts, and an AWS CodeBuild project to build, test, and deploy the app. The pipeline deploys a given CDK application as one or more AWS CloudFormation stacks.

With CloudFormation stacks, there is the possibility that someone can manually change the configuration of stack resources outside the purview of CloudFormation and the pipeline that deploys the stack. This causes the deployed resources to be inconsistent with the intent in the application, which is referred to as “drift”, a situation that can make the application’s behavior unpredictable. For example, when troubleshooting an application, if the application has drifted in production, it is difficult to reproduce the same behavior in a development environment. In other cases, it may introduce security vulnerabilities in the application. For example, an AWS EC2 SecurityGroup that was originally deployed to allow ingress traffic from a specific IP address might potentially be opened up to allow traffic from all IP addresses.

CloudFormation offers a drift detection feature for stacks and stack resources to detect configuration changes that are made outside of CloudFormation. The stack/resource is considered as drifted if its configuration does not match the expected configuration defined in the CloudFormation template and by extension the CDK code that synthesized it.

In this blog post you will see how CloudFormation drift detection can be integrated as a pre-deployment validation step in CDK Pipelines using an event driven approach.

Services and frameworks used in the post include CloudFormation, CodeBuild, Amazon EventBridge, AWS Lambda, Amazon DynamoDB, S3, and AWS CDK.

Solution overview

Amazon EventBridge is a serverless AWS service that offers an agile mechanism for the developers to spin up loosely coupled, event driven applications at scale. EventBridge supports routing of events between services via an event bus. EventBridge out of the box supports a default event bus for each account which receives events from AWS services. Last year, CloudFormation added a new feature that enables event notifications for changes made to CloudFormation-based stacks and resources. These notifications are accessible through Amazon EventBridge, allowing users to monitor and react to changes in their CloudFormation infrastructure using event-driven workflows. Our solution leverages the drift detection events that are now supported by EventBridge. The following architecture diagram depicts the flow of events involved in successfully performing drift detection in CDK Pipelines.

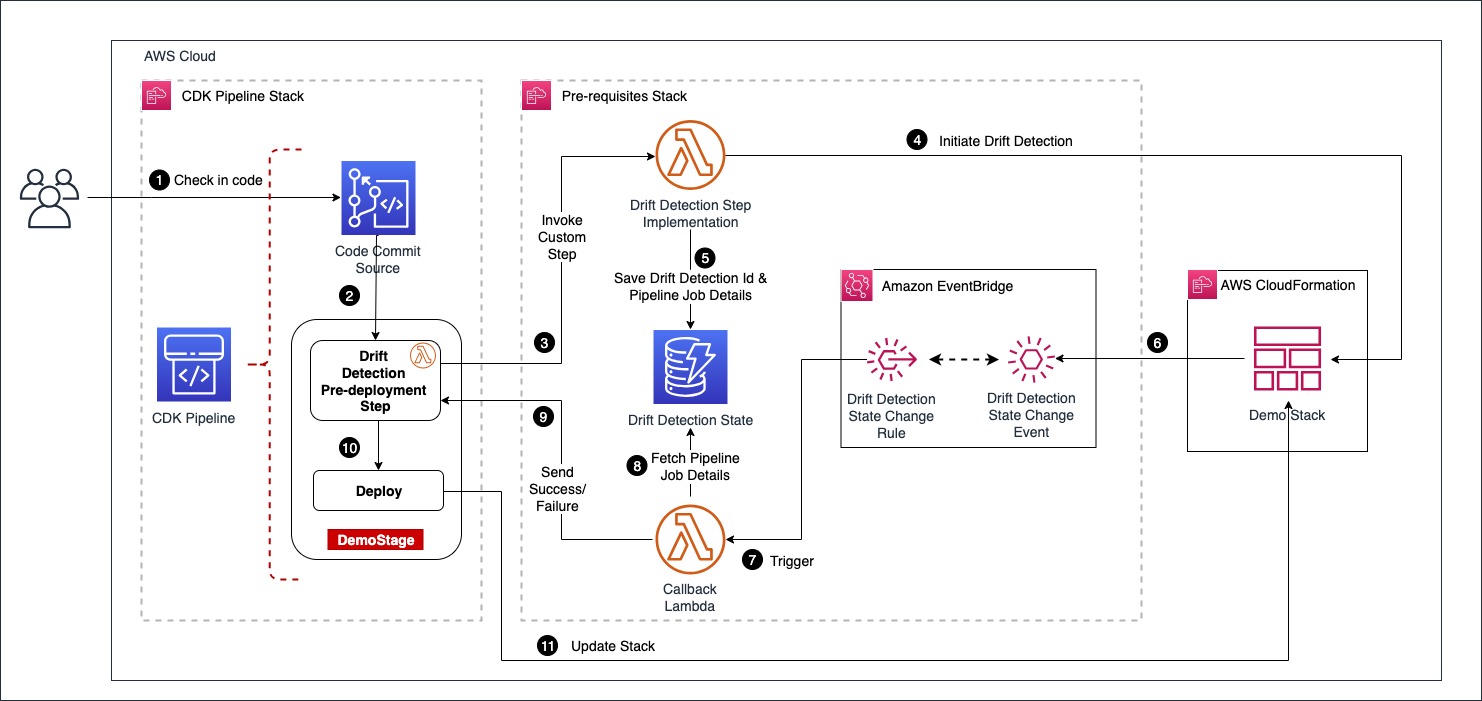
Architecture diagram

Architecture diagram

The user starts the pipeline by checking code into an AWS CodeCommit repo, which acts as the pipeline source. We have configured drift detection in the pipeline as a custom step backed by a lambda function. When the drift detection step invokes the provider lambda function, it first starts the drift detection on the CloudFormation stack Demo Stack and then saves the drift_detection_id along with pipeline_job_id in a DynamoDB table. In the meantime, the pipeline waits for a response on the status of drift detection.

The EventBridge rules are set up to capture the drift detection state change events for Demo Stack that are received by the default event bus. The callback lambda is registered as the intended target for the rules. When drift detection completes, it triggers the EventBridge rule which in turn invokes the callback lambda function with stack status as either DRIFTED or IN SYNC. The callback lambda function pulls the pipeline_job_id from DynamoDB and sends the appropriate status back to the pipeline, thus propelling the pipeline out of the wait state. If the stack is in the IN SYNC status, the callback lambda sends a success status and the pipeline continues with the deployment. If the stack is in the DRIFTED status, callback lambda sends failure status back to the pipeline and the pipeline run ends up in failure.

Solution Deep Dive

The solution deploys two stacks as shown in the above architecture diagram

  1. CDK Pipelines stack
  2. Pre-requisite stack

The CDK Pipelines stack defines a pipeline with a CodeCommit source and drift detection step integrated into it. The pre-requisite stack deploys following resources that are required by the CDK Pipelines stack.

  • A Lambda function that implements drift detection step
  • A DynamoDB table that holds drift_detection_id and pipeline_job_id
  • An Event bridge rule to capture “CloudFormation Drift Detection Status Change” event
  • A callback lambda function that evaluates status of drift detection and sends status back to the pipeline by looking up the data captured in DynamoDB.

The pre-requisites stack is deployed first, followed by the CDK Pipelines stack.

Defining drift detection step

CDK Pipelines offers a mechanism to define your own step that requires custom implementation. A step corresponds to a custom action in CodePipeline such as invoke lambda function. It can exist as a pre or post deployment action in a given stage of the pipeline. For example, your organization’s policies may require its CI/CD pipelines to run a security vulnerability scan as a prerequisite before deployment. You can build this as a custom step in your CDK Pipelines. In this post, you will use the same mechanism for adding the drift detection step in the pipeline.

You start by defining a class called DriftDetectionStep that extends Step and implements ICodePipelineActionFactory as shown in the following code snippet. The constructor accepts 3 parameters stackName, account, region as inputs. When the pipeline runs the step, it invokes the drift detection lambda function with these parameters wrapped inside userParameters variable. The function produceAction() adds the action to invoke drift detection lambda function to the pipeline stage.

Please note that the solution uses an SSM parameter to inject the lambda function ARN into the pipeline stack. So, we deploy the provider lambda function as part of pre-requisites stack before the pipeline stack and publish its ARN to the SSM parameter. The CDK code to deploy pre-requisites stack can be found here.

export class DriftDetectionStep
    extends Step
    implements pipelines.ICodePipelineActionFactory
{
    constructor(
        private readonly stackName: string,
        private readonly account: string,
        private readonly region: string
    ) {
        super(`DriftDetectionStep-${stackName}`);
    }

    public produceAction(
        stage: codepipeline.IStage,
        options: ProduceActionOptions
    ): CodePipelineActionFactoryResult {
        // Define the configuraton for the action that is added to the pipeline.
        stage.addAction(
            new cpactions.LambdaInvokeAction({
                actionName: options.actionName,
                runOrder: options.runOrder,
                lambda: lambda.Function.fromFunctionArn(
                    options.scope,
                    `InitiateDriftDetectLambda-${this.stackName}`,
                    ssm.StringParameter.valueForStringParameter(
                        options.scope,
                        SSM_PARAM_DRIFT_DETECT_LAMBDA_ARN
                    )
                ),
                // These are the parameters passed to the drift detection step implementaton provider lambda
                userParameters: {
                    stackName: this.stackName,
                    account: this.account,
                    region: this.region,
                },
            })
        );
        return {
            runOrdersConsumed: 1,
        };
    }
}

Configuring drift detection step in CDK Pipelines

Here you will see how to integrate the previously defined drift detection step into CDK Pipelines. The pipeline has a stage called DemoStage as shown in the following code snippet. During the construction of DemoStage, we declare drift detection as the pre-deployment step. This makes sure that the pipeline always does the drift detection check prior to deployment.

Please note that for every stack defined in the stage; we add a dedicated step to perform drift detection by instantiating the class DriftDetectionStep detailed in the prior section. Thus, this solution scales with the number of stacks defined per stage.

export class PipelineStack extends BaseStack {
    constructor(scope: Construct, id: string, props?: StackProps) {
        super(scope, id, props);

        const repo = new codecommit.Repository(this, 'DemoRepo', {
            repositoryName: `${this.node.tryGetContext('appName')}-repo`,
        });

        const pipeline = new CodePipeline(this, 'DemoPipeline', {
            synth: new ShellStep('synth', {
                input: CodePipelineSource.codeCommit(repo, 'main'),
                commands: ['./script-synth.sh'],
            }),
            crossAccountKeys: true,
            enableKeyRotation: true,
        });
        const demoStage = new DemoStage(this, 'DemoStage', {
            env: {
                account: this.account,
                region: this.region,
            },
        });
        const driftDetectionSteps: Step[] = [];
        for (const stackName of demoStage.stackNameList) {
            const step = new DriftDetectionStep(stackName, this.account, this.region);
            driftDetectionSteps.push(step);
        }
        pipeline.addStage(demoStage, {
            pre: driftDetectionSteps,
        });

Demo

Here you will go through the deployment steps for the solution and see drift detection in action.

Deploy the pre-requisites stack

Clone the repo from the GitHub location here. Navigate to the cloned folder and run script script-deploy.sh You can find detailed instructions in README.md

Deploy the CDK Pipelines stack

Clone the repo from the GitHub location here. Navigate to the cloned folder and run script script-deploy.sh. This deploys a pipeline with an empty CodeCommit repo as the source. The pipeline run ends up in failure, as shown below, because of the empty CodeCommit repo.

First run of the pipeline

Next, check in the code from the cloned repo into the CodeCommit source repo. You can find detailed instructions on that in README.md  This triggers the pipeline and pipeline finishes successfully, as shown below.

Pipeline run after first check in

The pipeline deploys two stacks DemoStackA and DemoStackB. Each of these stacks creates an S3 bucket.

CloudFormation stacks deployed after first run of the pipeline

Demonstrate drift detection

Locate the S3 bucket created by DemoStackA under resources, navigate to the S3 bucket and modify the tag aws-cdk:auto-delete-objects from true to false as shown below

DemoStackA resources

DemoStackA modify S3 tag

Now, go to the pipeline and trigger a new execution by clicking on Release Change

Run pipeline via Release Change tab

The pipeline run will now end in failure at the pre-deployment drift detection step.

Pipeline run after Drift Detection failure

Cleanup

Please follow the steps below to clean up all the stacks.

  1. Navigate to S3 console and empty the buckets created by stacks DemoStackA and DemoStackB.
  2. Navigate to the CloudFormation console and delete stacks DemoStackA and DemoStackB, since deleting CDK Pipelines stack does not delete the application stacks that the pipeline deploys.
  3. Delete the CDK Pipelines stack cdk-drift-detect-demo-pipeline
  4. Delete the pre-requisites stack cdk-drift-detect-demo-drift-detection-prereq

Conclusion

In this post, I showed how to add a custom implementation step in CDK Pipelines. I also used that mechanism to integrate a drift detection check as a pre-deployment step. This allows us to validate the integrity of a CloudFormation Stack before its deployment. Since the validation is integrated into the pipeline, it is easier to manage the solution in one place as part of the overarching pipeline. Give the solution a try, and then see if you can incorporate it into your organization’s delivery pipelines.

About the author:

Damodar Shenvi Wagle

Damodar Shenvi Wagle is a Senior Cloud Application Architect at AWS Professional Services. His areas of expertise include architecting serverless solutions, CI/CD, and automation.

Amazon Pinpoint 10DLC Campaign Types and Quotas for SMS

Post Syndicated from Tyler Holmes original https://aws.amazon.com/blogs/messaging-and-targeting/amazon-pinpoint-10dlc-campaign-types-and-quotas-for-sms/

The following 10DLC Campaigns, or, Use Cases outlined in Table 2 are currently supported by Amazon Pinpoint. As part of the process to register for sending SMS to US based phone numbers you must select at least one Campaign that will be associated with the 10DLC number you procure. If you require more than one Use Case then you will need more than one 10DLC, or you can select the standard mixed use case which supports lower volumes of messages. Throughput is determined based on the company vetting score of the registered sender of the message and what is being sent, not on the amount of numbers associated with the Campaign. For a breakdown of vetting scores and quotas see below:

Throughput and Volume Quotas for 10DLC Vetted Companies

*Note that by default each number associated to a 10DLC campaign supports 1 MPS. In order to increase your numbers to match what your campaign qualifies for by carriers you will be required to submit a MPS increase request.

Table 1

Vetting Score Message Parts per Second (MPS) (AT&T Limits) Maximum daily messages (T-Mobile & Sprint)
High(75-100) 75 200,000
Medium-High(50-74) 40 40,000
Medium-Low(1-49) 4 10,000
Basic(0, Skipped Vetting) 0.2 2,000

Standard 10DLC Campaign Use Cases

Select the campaign that most closely aligns with your use case(s).

Table 2

Campaign/Use-Case Name Intended Use Cases
Account Notifications Status notifications about an account that the recipient is a part of or owns
Customer Care Communications related to support or account management
Delivery Notifications Notifications about the status of a delivery of a product or service
Fraud Alert Messaging Notifications related to potential fraudulent activity
Higher Education Messaging Messaging originating from colleges, universities, or other post-secondary education institutions
Low Volume Small throughput, any combination of use-cases. Examples include: test, demo accounts
Marketing Messaging Promotional content related to sales or other offers
Mixed Use Cases Covers multiple use cases such as Account Notifications and Delivery Notifications. Mixed campaigns have lower throughput than dedicated ones
Polling and Voting – Not for Political Use Delivering messages containing customer surveys or other voting related actions. Not for political use
Public Service Announcements (PSA) Messages intended to raise awareness of a particular topic
Security Alerts Notifications related to a compromised software or hardware system that requires recipients to take an action
Two Factor Authentication(2FA) or One-Time Password(OTP) Authentication, account verifications, or one-time passcode
Special Use Cases Currently Pinpoint supports only the following special use cases. These may require different registration processes and/or fees than the Standard Use Cases above
Charity / 501(c)(3) Nonprofit Communications from a registered company classified as a 501(c)(3). Does not include religious organizations

China Hacked Japan’s Military Networks

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/china-hacked-japans-military-networks.html

The NSA discovered the intrusion in 2020—we don’t know how—and alerted the Japanese. The Washington Post has the story:

The hackers had deep, persistent access and appeared to be after anything they could get their hands on—plans, capabilities, assessments of military shortcomings, according to three former senior U.S. officials, who were among a dozen current and former U.S. and Japanese officials interviewed, who spoke on the condition of anonymity because of the matter’s sensitivity.

[…]

The 2020 penetration was so disturbing that Gen. Paul Nakasone, the head of the NSA and U.S. Cyber Command, and Matthew Pottinger, who was White House deputy national security adviser at the time, raced to Tokyo. They briefed the defense minister, who was so concerned that he arranged for them to alert the prime minister himself.

Beijing, they told the Japanese officials, had breached Tokyo’s defense networks, making it one of the most damaging hacks in that country’s modern history.

More analysis.

Friday Squid Blogging: NIWA Annual Squid Survey

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/friday-squid-blogging-niwa-annual-squid-survey.html

Results from the National Institute of Water and Atmospheric Research Limited annual squid survey:

This year, the team unearthed spectacular large hooked squids, weighing about 15kg and sitting at 2m long, a Taningia—­which has the largest known light organs in the animal kingdom­—and a few species that remain very rare in collections worldwide, such as the “scaled” squid Lepidoteuthis and the Batoteuthis skolops.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

The Inability to Simultaneously Verify Sentience, Location, and Identity

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/the-inability-to-simultaneously-verify-sentience-location-and-identity.html

Really interesting “systematization of knowledge” paper:

“SoK: The Ghost Trilemma”

Abstract: Trolls, bots, and sybils distort online discourse and compromise the security of networked platforms. User identity is central to the vectors of attack and manipulation employed in these contexts. However it has long seemed that, try as it might, the security community has been unable to stem the rising tide of such problems. We posit the Ghost Trilemma, that there are three key properties of identity—sentience, location, and uniqueness—that cannot be simultaneously verified in a fully-decentralized setting. Many fully-decentralized systems—whether for communication or social coordination—grapple with this trilemma in some way, perhaps unknowingly. In this Systematization of Knowledge (SoK) paper, we examine the design space, use cases, problems with prior approaches, and possible paths forward. We sketch a proof of this trilemma and outline options for practical, incrementally deployable schemes to achieve an acceptable tradeoff of trust in centralized trust anchors, decentralized operation, and an ability to withstand a range of attacks, while protecting user privacy.

I think this conceptualization makes sense, and explains a lot.

Cryptographic Flaw in Libbitcoin Explorer Cryptocurrency Wallet

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/cryptographic-flaw-in-libbitcoin-explorer-cryptocurrency-wallet.html

Cryptographic flaws still matter. Here’s a flaw in the random-number generator used to create private keys. The seed has only 32 bits of entropy.

Seems like this flaw is being exploited in the wild.

EDITED TO ADD (8/14): A good explainer.

Using Machine Learning to Detect Keystrokes

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/using-machine-learning-to-detect-keystrokes.html

Researchers have trained a ML model to detect keystrokes by sound with 95% accuracy.

“A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards”

Abstract: With recent developments in deep learning, the ubiquity of microphones and the rise in online services via personal devices, acoustic side channel attacks present a greater threat to keyboards than ever. This paper presents a practical implementation of a state-of-the-art deep learning model in order to classify laptop keystrokes, using a smartphone integrated microphone. When trained on keystrokes recorded by a nearby phone, the classifier achieved an accuracy of 95%, the highest accuracy seen without the use of a language model. When trained on keystrokes recorded using the video-conferencing software Zoom, an accuracy of 93% was achieved, a new best for the medium. Our results prove the practicality of these side channel attacks via off-the-shelf equipment and algorithms. We discuss a series of mitigation methods to protect users against these series of attacks.

News article.

How to Send SMS Using Configurations Sets with Amazon Pinpoint

Post Syndicated from Tyler Holmes original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-send-sms-using-configurations-sets-with-amazon-pinpoint/

In a previous blog post we walked through how to manage opt-outs for SMS in Amazon Pinpoint using the V2 SMS and Voice API. The post detailed a scenario where a user needed to manage multiple use-cases such as marketing and One-Time Password (OTP) or Multi-Factor Authentication (MFA). This works great if all of your data can be streamed to a single location, but what if you have multiple business units or you are an Independent Software Vendor (ISV) and need to manage SMS sending for multiple customers? You need a way to not only manage multiple use-cases and opt-out lists, but also sender details and separate event destinations for metrics. Read on to learn how to combine SMS Opt-Out Lists with Configuration Sets to simplify your sending and solve your multi-tenant challenge.

Prerequisites

  • In order to manage Configuration Sets you need to use the V2 API for SMS and voice
  • You must Purchase/Register an Origination Identity (OID) for each use-case in each country you plan to support.
    • Example: If you are sending marketing materials and OTP messages in the US and are using a short code then you will need to purchase at least two short codes (one for each use-case) and register each use-case.
    • If you need help determining what OID you need use this guide.

The Scenario:
For the sake of simplicity our scenario will use two different senders that need to manage two distinct use-cases but these steps can scale as you need.

SMS Sender 1 Details:

  • Sending only in the US
  • Sending OTP via a US Short Code
  • Sending Marketing messages via a 10DLC
    • Send text events to an Amazon Kinesis Data Firehose destination
    • Send text events to an Amazon CloudWatch destination

SMS Sender 2 Details:

  • Sending SMS Globally
  • Sending OTP via multiple country specific originators
    • Send events to an Amazon Kinesis Data Firehose destination
    • Send all events to an Amazon CloudWatch destination

The V2 SMS and Voice API has several helpful actions to configure this scenario above, some of which will expand upon our previous blog post that covered managing SMS opt-outs so make sure to read that one first and have it handy as you review.

What is a Configuration Set for SMS?

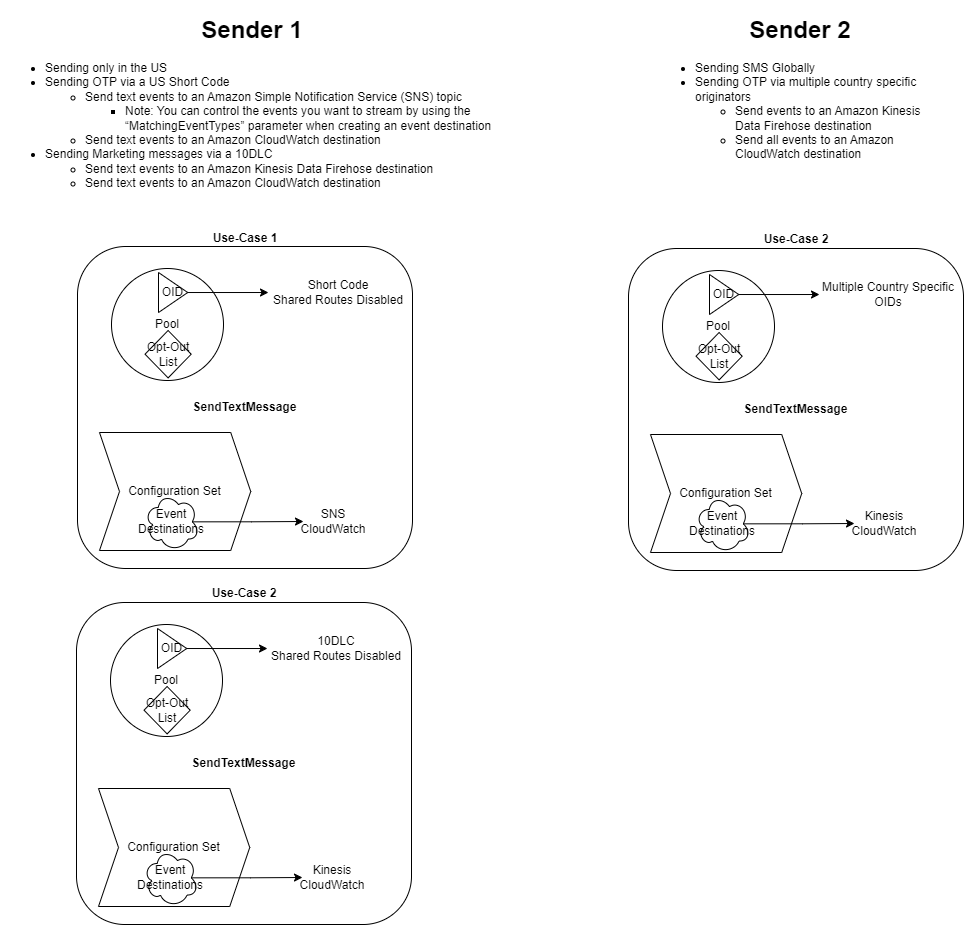
A Configuration Set is a container that is used to hold information about Event Destinations as well as rules that you apply to the SMS messages that you send. Configuration Sets are used when sending messages with the SendTextMessage Action in the V2 API for SMS and voice. When you use SendTextMessage you can specify a Configuration Set that determines how the messages are treated and where the events from that particular send are streamed. The image below explains the concepts we will walk through in this post.


How to Create Configuration Sets and Send SMS
Below we will walk through the steps needed to configure each of the above scenarios. Note that the default quota for Configuration Sets is 25 per account but this can be increased if needed

  • Scenario 1 –
    • Short Code Configuration
      • Create a Pool for the US Short Code delivering OTP messages
        • Associate the short code to that Pool by setting “OriginationIdentity” using the PhoneNumberArn of your US Short Code
          • You can use DescribePhoneNumbers to find the values for PhoneNumberArn
          • Note: You can have multiple OIDs per Pool if necessary
          • Note: Opt-Out Lists of OIDs and Pools must match. If you previously associated an Opt-Out List to any OIDs you may need to update those OIDs to match that of the Pool prior to associating it with the Pool
        • Set the IsoCountryCode to “US”
      • Use the “UpdatePool” action to ensure we only send to US phone numbers as well as to create an Opt-Out List specifically for the OTP use-case
        • Set “SharedRoutesEnabled” to False. This will ensure that only the OIDs in this pool will be used to send messages.
          • Since we will only have a US Shortcode in this pool then only US based phone numbers will be sent messages, other destination phone numbers will generate a ConflictException error
            • An error occurred (ConflictException) when calling the SendTextMessage operation: Conflict Occurred – Reason=”NO_ORIGINATION_IDENTITIES_FOUND”
        • Set an Opt-Out List for the Pool by specifying the “OptOutListName”
      • Use the “PutKeyword” action to create at least one Opt-In Keyword
        • This will allow destination numbers to opt back into your use-case
      • Create a Configuration Set
        • This is a container for your Event Destinations which you will set up next. Each configuration set can contain between 0 and 5 event destinations. Each event destination can contain a reference to a single destination, such as a CloudWatch or Kinesis Data Firehose destination
        • Give your Configuration a descriptive name by setting “ConfigurationSetName”
      • Create an SNS Topic that will receive all of the events. Dependent on your needs you can decide where you want to publish these events. Your options are:
      • Create a CloudWatch Log Group that will receive all of the events you would like to log
      • Create Event Destinations – Each event destination can contain a reference to a single destination, since we are adding two destinations (SNS and CloudWatch) we will need to make this call twice, once for each destination
        • Create the SNS destination.
          • Set the “ConfigurationSetName” to the Configuration Set you just created
          • Set “MatchingEventTypes” to the event types you are wanting to log
          • Set the SNS Event Destination
            • Set the “TopicArn”
        • Create the CloudWatch Destination
          • Set the “ConfigurationSetName” to the Configuration Set you just created
          • Set “MatchingEventTypes” to the event types you are wanting to log
          • Set “IamRoleArn” to the ARN of an Amazon Identity and Access Management (IAM) role that is able to write event data to an Amazon CloudWatch destination
          • Set the “LogGroupArn” to the Log Group in CloudWatch you want the events to stream to
    • 10DLC Configuration
        • Create a Pool for the 10DLC delivering Marketing messages
          • Associate the 10DLC to that Pool by setting “OriginationIdentity” using the PhoneNumberArn of your 10DLC
            • You can use DescribePhoneNumbers to find the values for PhoneNumberArn
            • Note: You can have multiple OIDs per Pool if necessary
            • Note: Opt-Out Lists of OIDs and Pools must match, so if you previously associated an Opt-Out List to any OIDs you may need to update those OIDs to match that of the Pool prior to associating it with the Pool
          • Set the IsoCountryCode to “US”
        • Use the “UpdatePool” action to ensure we only send to US phone numbers as well as to create an Opt-Out List specifically for the Marketing use-case
          • Set “SharedRoutesEnabled” to False. This will ensure that only the OIDs in this pool will be used to send messages.
            • Since we will only have a 10DLC in this pool then only US based phone numbers will be sent messages, other destination phone numbers will generate an error
          • Set an Opt-Out List for the Pool by specifying the “OptOutListName”
        • Use the “PutKeyword” action to create at least one Opt-In Keyword
        • Create a Configuration Set
          • Give your Configuration a descriptive name by setting “ConfigurationSetName”
        • Create a Kinesis Data Firehose Delivery Stream that will receive all of the events.
        • Create a CloudWatch Log Group that will receive all of the events you would like to log
        • Create Event Destinations – Each event destination can contain a reference to a single destination. We are adding two destinations (SNS and CloudWatch) so we need to make this call twice, once for each destination
          • Create the Kinesis destination.
            • Set the “ConfigurationSetName” to the Configuration Set you just created
            • Set “MatchingEventTypes” to the event types you are wanting to log
            • Set the Kinesis Event Destination
              • Set the “DeliveryStreamArn” to the Stream you created earlier
              • Set the “IamRoleArn” to the ARN of an IAM role that is able to write event data to an Amazon Firehose destination
          • Create the CloudWatch Destination
            • Set the “ConfigurationSetName” to the Configuration Set you just created
            • Set “MatchingEventTypes” to the event types you are wanting to log
            • Set “IamRoleArn” to an IAM role that is able to write event data to an Amazon CloudWatch destination
            • Set the “LogGroupArn” to the Log Group in CloudWatch you want the events to stream to
  • Scenario 2
    • Global OTP Configuration
      • Create a Pool for delivering the OTP messages
        • Associate all of your OIDs being used to that Pool
          • You can use DescribePhoneNumbers to find the values for PhoneNumberArn
          • Note: Opt-Out Lists of OIDs and Pools must match, so if you previously associated an Opt-Out List to any OIDs you may need to update those OIDs to match that of the Pool prior to associating it with the Pool
      • Use the “UpdatePool” action to create an Opt-Out List specifically for the OTP use-case.
        • Set an Opt-Out List for the Pool by specifying the “OptOutListName”
      • Use the “PutKeyword” action to create at least one Opt-In Keyword
        • This will allow destination numbers to opt back into your use-case, in this case OTP
      • Create a Configuration Set
        • Give your Configuration a descriptive name by setting “ConfigurationSetName”
      • Create a Kinesis Data Firehose Delivery Stream that will receive all of the events
      • Create a CloudWatch Log Group that will receive all of the events you would like to log
      • Create Event Destinations – Each event destination can contain a reference to a single destination, since we are adding two destinations (SNS and CloudWatch) we will need to make this call twice, once for each destination
        • Create the Kinesis destination.
          • Set the “ConfigurationSetName” to the Configuration Set you just created
          • Set “MatchingEventTypes” to the event types you are wanting to log
          • Set the Kinesis Event Destination
            • Set the “DeliveryStreamArn” to the Stream you created earlier
            • Set the “IamRoleArn” to the ARN of an IAM role that is able to write event data to an Amazon Firehose destination
        • Create the CloudWatch Destination
          • Set the “ConfigurationSetName” to the Configuration Set you just created
          • Set “MatchingEventTypes” to the event types you are wanting to log
          • Set “IamRoleArn” to an IAM role that is able to write event data to an Amazon CloudWatch destination
          • Set the “LogGroupArn” to the Log Group in CloudWatch you want the events to stream to

Your configuration should look like this once you have completed the above steps

How to Send Your Messages

  • Send your SMS with the “SendTextMessage” action
    • Set the “ConfigurationSetName” using either the ConfigurationSetName or ConfigurationSetArn
      • You can find these using the “DescribeConfigurationSets” action
      • This field is used for any country-specific registration requirements. Currently, this setting is only used when you send messages to recipients in India using a sender ID.
    • Use either PoolId, or PoolArn for “OriginationIdentity”

Conclusion

In this post you have learned how to create Configuration Sets that give you more control over how you send SMS. Using Configuration Sets allows you to simplify your sending while maintaining multiple sending configurations and event destinations . The V2 API for SMS and Voice has many more useful actions not possible with the V1 API so we encourage you to explore how it can further help you simplify and automate your applications.

Review the documentation for the V2 SMS and Voice API here
Confirm the origination IDs you will need here
Check out the support tiers comparison here

Resources
https://docs.aws.amazon.com/pinpoint/latest/apireference_smsvoicev2/Welcome.html
https://docs.aws.amazon.com/pinpoint/latest/userguide/channels-sms-originating-identities-choosing.html
https://docs.aws.amazon.com/pinpoint/latest/userguide/channels-sms-limitations-opt-out.html
https://docs.aws.amazon.com/pinpoint/latest/developerguide/sms-voice-v2-pools.html
https://docs.aws.amazon.com/pinpoint/latest/developerguide/sms-voice-v2-configuration-sets.html
https://docs.aws.amazon.com/pinpoint/latest/developerguide/sms-voice-v2-keywords.html

AWS Weekly Roundup – AWS Storage Day, AWS Israel (Tel Aviv) Region, and More – Aug 8, 2023

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-storage-day-aws-israel-tel-aviv-region-and-more-aug-8-2023/

(Editor’s note: Today, we are changing the title of this regular weekly post from AWS Week in Review to AWS Weekly Roundup to better reflect the mix of recent top news and announcements as well as upcoming events you won’t want to miss.)


It’s taken me some time to finally be comfortable with being in front of a camera, a strange thing for a Developer Advocate to say I know! Last week I joined a couple of my team-mates at the AWS London Studios to record a series of videos that will be published in our Build On AWS YouTube Channel. Build On AWS is for the hands-on, technical AWS cloud builder who wants to become more agile and innovate faster. In the channel, you’ll find dynamic, high-quality content that’s designed for developers, by developers!

This video tells you more about what you’ll find in the channel. Check it out and consider subscribing to not miss out when we publish new content.

Now on to the AWS updates. There was a lot of news related to AWS last week, and I’ve compiled a few announcements and upcoming events you need to know about. Let’s get started!

Last Week’s Launches
Here are a few launches from last week that you might have missed:

Microsoft 365 Apps for enterprise now available on Amazon WorkSpaces servicesAmazon WorkSpaces is a fully managed, secure, and reliable virtual desktop in the AWS Cloud. With Amazon WorkSpaces, you improve IT agility and maximize user experience, while only paying for the infrastructure that you use. We announced the availability of Microsoft 365 Apps for enterprise on Amazon WorkSpaces. You can bring your own Microsoft 365 licenses (if they meet Microsoft’s licensing requirements) and activate the applications at no additional cost to run Microsoft 365 Apps for enterprise on Amazon WorkSpaces services.

AWS Israel (Tel Aviv) Region is Now Open – You can now securely store data in Israel while serving users in the vicinity with even lower latency. This is because last week we launched the Tel Aviv Region to give customers an additional option for running applications and serving users from data centers located in Israel.

Amazon Connect Launches – This is one of my favorite AWS services to write about because of how Amazon Connect is changing our customers’ engagement with their own customers. Last week, Amazon Connect announced automatic activity scheduling based on shift duration, custom flow block titles, and archiving and deleting flows from the UI, to name a few.

Other AWS News
A few more news items and blog posts you might have missed:

Customizable thresholds for health events supported on Amazon CloudWatch Internet Monitor – Until this announcement, the default threshold for overall availability and performance scores to invoke a health event was 95 percent. Now, you can customize the thresholds for when to invoke a health event for internet-facing traffic between your end users and your applications hosted on AWS.

Improved AWS Backup performance for Amazon S3 buckets – Now you can speed up your initial Amazon S3 backup workflow and back up buckets with more than 3 billion objects due to improvements to the speed of backups by up to 10x for buckets with more than 300 million objects. This performance improvement is automatically enabled at no additional cost in all Regions where AWS Backup support for Amazon S3 is available.

For AWS open-source news and updates, check out the latest newsletter curated by my colleague Ricardo Sueiras to bring you the most recent updates on open-source projects, posts, events, and more.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Upcoming AWS Events
We have the following upcoming events:

AWS Storage Day (August 9) – A one-day virtual event where you’ll learn how to prepare for AI/ML with the storage decisions you make now, how to do more with your budget by optimizing storage costs for on-premises and cloud data, and how to deliver holistic data protection for your organization, including recovery planning to help protect against ransomware. Learn more and register here.

AWS Summit Mexico City (August 30)Sign up for the Summit to connect and collaborate with other like-minded folks while learning about AWS.

AWS Community Days (August 12, 19) – Join these community-led conferences where event logistics and content are planned, sourced, and delivered by community leaders: Colombia (August 12), and West Africa (August 19).


P.S. We’re focused on improving our content to provide a better customer experience, and we need your feedback to do so. Take this quick survey to share insights on your experience with the AWS Blog. Note that this survey is hosted by an external company, so the link doesn’t lead to our website. AWS handles your information as described in the AWS Privacy Notice.

– Veliswa

You Can’t Rush Post-Quantum-Computing Cryptography Standards

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/you-cant-rush-post-quantum-computing-standards.html

I just read an article complaining that NIST is taking too long in finalizing its post-quantum-computing cryptography standards.

This process has been going on since 2016, and since that time there has been a huge increase in quantum technology and an equally large increase in quantum understanding and interest. Yet seven years later, we have only four algorithms, although last week NIST announced that a number of other candidates are under consideration, a process that is expected to take “several years.

The delay in developing quantum-resistant algorithms is especially troubling given the time it will take to get those products to market. It generally takes four to six years with a new standard for a vendor to develop an ASIC to implement the standard, and it then takes time for the vendor to get the product validated, which seems to be taking a troubling amount of time.

Yes, the process will take several years, and you really don’t want to rush it. I wrote this last year:

Ian Cassels, British mathematician and World War II cryptanalyst, once said that “cryptography is a mixture of mathematics and muddle, and without the muddle the mathematics can be used against you.” This mixture is particularly difficult to achieve with public-key algorithms, which rely on the mathematics for their security in a way that symmetric algorithms do not. We got lucky with RSA and related algorithms: their mathematics hinge on the problem of factoring, which turned out to be robustly difficult. Post-quantum algorithms rely on other mathematical disciplines and problems­—code-based cryptography, hash-based cryptography, lattice-based cryptography, multivariate cryptography, and so on­—whose mathematics are both more complicated and less well-understood. We’re seeing these breaks because those core mathematical problems aren’t nearly as well-studied as factoring is.

[…]

As the new cryptanalytic results demonstrate, we’re still learning a lot about how to turn hard mathematical problems into public-key cryptosystems. We have too much math and an inability to add more muddle, and that results in algorithms that are vulnerable to advances in mathematics. More cryptanalytic results are coming, and more algorithms are going to be broken.

As to the long time it takes to get new encryption products to market, work on shortening it:

The moral is the need for cryptographic agility. It’s not enough to implement a single standard; it’s vital that our systems be able to easily swap in new algorithms when required.

Whatever NIST comes up with, expect that it will get broken sooner than we all want. It’s the nature of these trap-door functions we’re using for public-key cryptography.

Microsoft Signing Key Stolen by Chinese

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/microsoft-signing-key-stolen-by-chinese.html

A bunch of networks, including US Government networks, have been hacked by the Chinese. The hackers used forged authentication tokens to access user email, using a stolen Microsoft Azure account consumer signing key. Congress wants answers. The phrase “negligent security practices” is being tossed about—and with good reason. Master signing keys are not supposed to be left around, waiting to be stolen.

Actually, two things went badly wrong here. The first is that Azure accepted an expired signing key, implying a vulnerability in whatever is supposed to check key validity. The second is that this key was supposed to remain in the the system’s Hardware Security Module—and not be in software. This implies a really serious breach of good security practice. The fact that Microsoft has not been forthcoming about the details of what happened tell me that the details are really bad.

I believe this all traces back to SolarWinds. In addition to Russia inserting malware into a SolarWinds update, China used a different SolarWinds vulnerability to break into networks. We know that Russia accessed Microsoft source code in that attack. I have heard from informed government officials that China used their SolarWinds vulnerability to break into Microsoft and access source code, including Azure’s.

I think we are grossly underestimating the long-term results of the SolarWinds attacks. That backdoored update was downloaded by over 14,000 networks worldwide. Organizations patched their networks, but not before Russia—and others—used the vulnerability to enter those networks. And once someone is in a network, it’s really hard to be sure that you’ve kicked them out.

Sophisticated threat actors are realizing that stealing source code of infrastructure providers, and then combing that code for vulnerabilities, is an excellent way to break into organizations who use those infrastructure providers. Attackers like Russia and China—and presumably the US as well—are prioritizing going after those providers.

News articles.

EDITED TO ADD: Commentary:

This is from Microsoft’s explanation. The China attackers “acquired an inactive MSA consumer signing key and used it to forge authentication tokens for Azure AD enterprise and MSA consumer to access OWA and Outlook.com. All MSA keys active prior to the incident—including the actor-acquired MSA signing key—have been invalidated. Azure AD keys were not impacted. Though the key was intended only for MSA accounts, a validation issue allowed this key to be trusted for signing Azure AD tokens. The actor was able to obtain new access tokens by presenting one previously issued from this API due to a design flaw. This flaw in the GetAccessTokenForResourceAPI has since been fixed to only accept tokens issued from Azure AD or MSA respectively. The actor used these tokens to retrieve mail messages from the OWA API.”

Political Milestones for AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/political-milestones-for-ai.html

ChatGPT was released just nine months ago, and we are still learning how it will affect our daily lives, our careers, and even our systems of self-governance.

But when it comes to how AI may threaten our democracy, much of the public conversation lacks imagination. People talk about the danger of campaigns that attack opponents with fake images (or fake audio or video) because we already have decades of experience dealing with doctored images. We’re on the lookout for foreign governments that spread misinformation because we were traumatized by the 2016 US presidential election. And we worry that AI-generated opinions will swamp the political preferences of real people because we’ve seen political “astroturfing”—the use of fake online accounts to give the illusion of support for a policy—grow for decades.

Threats of this sort seem urgent and disturbing because they’re salient. We know what to look for, and we can easily imagine their effects.

The truth is, the future will be much more interesting. And even some of the most stupendous potential impacts of AI on politics won’t be all bad. We can draw some fairly straight lines between the current capabilities of AI tools and real-world outcomes that, by the standards of current public understanding, seem truly startling.

With this in mind, we propose six milestones that will herald a new era of democratic politics driven by AI. All feel achievable—perhaps not with today’s technology and levels of AI adoption, but very possibly in the near future.

Good benchmarks should be meaningful, representing significant outcomes that come with real-world consequences. They should be plausible; they must be realistically achievable in the foreseeable future. And they should be observable—we should be able to recognize when they’ve been achieved.

Worries about AI swaying an election will very likely fail the observability test. While the risks of election manipulation through the robotic promotion of a candidate’s or party’s interests is a legitimate threat, elections are massively complex. Just as the debate continues to rage over why and how Donald Trump won the presidency in 2016, we’re unlikely to be able to attribute a surprising electoral outcome to any particular AI intervention.

Thinking further into the future: Could an AI candidate ever be elected to office? In the world of speculative fiction, from The Twilight Zone to Black Mirror, there is growing interest in the possibility of an AI or technologically assisted, otherwise-not-traditionally-eligible candidate winning an election. In an era where deepfaked videos can misrepresent the views and actions of human candidates and human politicians can choose to be represented by AI avatars or even robots, it is certainly possible for an AI candidate to mimic the media presence of a politician. Virtual politicians have received votes in national elections, for example in Russia in 2017. But this doesn’t pass the plausibility test. The voting public and legal establishment are likely to accept more and more automation and assistance supported by AI, but the age of non-human elected officials is far off.

Let’s start with some milestones that are already on the cusp of reality. These are achievements that seem well within the technical scope of existing AI technologies and for which the groundwork has already been laid.

Milestone #1: The acceptance by a legislature or agency of a testimony or comment generated by, and submitted under the name of, an AI.

Arguably, we’ve already seen legislation drafted by AI, albeit under the direction of human users and introduced by human legislators. After some early examples of bills written by AIs were introduced in Massachusetts and the US House of Representatives, many major legislative bodies have had their “first bill written by AI,” “used ChatGPT to generate committee remarks,” or “first floor speech written by AI” events.

Many of these bills and speeches are more stunt than serious, and they have received more criticism than consideration. They are short, have trivial levels of policy substance, or were heavily edited or guided by human legislators (through highly specific prompts to large language model-based AI tools like ChatGPT).

The interesting milestone along these lines will be the acceptance of testimony on legislation, or a comment submitted to an agency, drafted entirely by AI. To be sure, a large fraction of all writing going forward will be assisted by—and will truly benefit from—AI assistive technologies. So to avoid making this milestone trivial, we have to add the second clause: “submitted under the name of the AI.”

What would make this benchmark significant is the submission under the AI’s own name; that is, the acceptance by a governing body of the AI as proffering a legitimate perspective in public debate. Regardless of the public fervor over AI, this one won’t take long. The New York Times has published a letter under the name of ChatGPT (responding to an opinion piece we wrote), and legislators are already turning to AI to write high-profile opening remarks at committee hearings.

Milestone #2: The adoption of the first novel legislative amendment to a bill written by AI.

Moving beyond testimony, there is an immediate pathway for AI-generated policies to become law: microlegislation. This involves making tweaks to existing laws or bills that are tuned to serve some particular interest. It is a natural starting point for AI because it’s tightly scoped, involving small changes guided by a clear directive associated with a well-defined purpose.

By design, microlegislation is often implemented surreptitiously. It may even be filed anonymously within a deluge of other amendments to obscure its intended beneficiary. For that reason, microlegislation can often be bad for society, and it is ripe for exploitation by generative AI that would otherwise be subject to heavy scrutiny from a polity on guard for risks posed by AI.

Milestone #3: AI-generated political messaging outscores campaign consultant recommendations in poll testing.

Some of the most important near-term implications of AI for politics will happen largely behind closed doors. Like everyone else, political campaigners and pollsters will turn to AI to help with their jobs. We’re already seeing campaigners turn to AI-generated images to manufacture social content and pollsters simulate results using AI-generated respondents.

The next step in this evolution is political messaging developed by AI. A mainstay of the campaigner’s toolbox today is the message testing survey, where a few alternate formulations of a position are written down and tested with audiences to see which will generate more attention and a more positive response. Just as an experienced political pollster can anticipate effective messaging strategies pretty well based on observations from past campaigns and their impression of the state of the public debate, so can an AI trained on reams of public discourse, campaign rhetoric, and political reporting.

With these near-term milestones firmly in sight, let’s look further to some truly revolutionary possibilities. While these concepts may have seemed absurd just a year ago, they are increasingly conceivable with either current or near-future technologies.

Milestone #4: AI creates a political party with its own platform, attracting human candidates who win elections.

While an AI is unlikely to be allowed to run for and hold office, it is plausible that one may be able to found a political party. An AI could generate a political platform calculated to attract the interest of some cross-section of the public and, acting independently or through a human intermediary (hired help, like a political consultant or legal firm), could register formally as a political party. It could collect signatures to win a place on ballots and attract human candidates to run for office under its banner.

A big step in this direction has already been taken, via the campaign of the Danish Synthetic Party in 2022. An artist collective in Denmark created an AI chatbot to interact with human members of its community on Discord, exploring political ideology in conversation with them and on the basis of an analysis of historical party platforms in the country. All this happened with earlier generations of general purpose AI, not current systems like ChatGPT. However, the party failed to receive enough signatures to earn a spot on the ballot, and therefore did not win parliamentary representation.

Future AI-led efforts may succeed. One could imagine a generative AI with skills at the level of or beyond today’s leading technologies could formulate a set of policy positions targeted to build support among people of a specific demographic, or even an effective consensus platform capable of attracting broad-based support. Particularly in a European-style multiparty system, we can imagine a new party with a strong news hook—an AI at its core—winning attention and votes.

Milestone #5: AI autonomously generates profit and makes political campaign contributions.

Let’s turn next to the essential capability of modern politics: fundraising. “An entity capable of directing contributions to a campaign fund” might be a realpolitik definition of a political actor, and AI is potentially capable of this.

Like a human, an AI could conceivably generate contributions to a political campaign in a variety of ways. It could take a seed investment from a human controlling the AI and invest it to yield a return. It could start a business that generates revenue. There is growing interest and experimentation in auto-hustling: AI agents that set about autonomously growing businesses or otherwise generating profit. While ChatGPT-generated businesses may not yet have taken the world by storm, this possibility is in the same spirit as the algorithmic agents powering modern high-speed trading and so-called autonomous finance capabilities that are already helping to automate business and financial decisions.

Or, like most political entrepreneurs, AI could generate political messaging to convince humans to spend their own money on a defined campaign or cause. The AI would likely need to have some humans in the loop, and register its activities to the government (in the US context, as officers of a 501(c)(4) or political action committee).

Milestone #6: AI achieves a coordinated policy outcome across multiple jurisdictions.

Lastly, we come to the most meaningful of impacts: achieving outcomes in public policy. Even if AI cannot—now or in the future—be said to have its own desires or preferences, it could be programmed by humans to have a goal, such as lowering taxes or relieving a market regulation.

An AI has many of the same tools humans use to achieve these ends. It may advocate, formulating messaging and promoting ideas through digital channels like social media posts and videos. It may lobby, directing ideas and influence to key policymakers, even writing legislation. It may spend; see milestone #5.

The “multiple jurisdictions” piece is key to this milestone. A single law passed may be reasonably attributed to myriad factors: a charismatic champion, a political movement, a change in circumstances. The influence of any one actor, such as an AI, will be more demonstrable if it is successful simultaneously in many different places. And the digital scalability of AI gives it a special advantage in achieving these kinds of coordinated outcomes.

The greatest challenge to most of these milestones is their observability: will we know it when we see it? The first campaign consultant whose ideas lose out to an AI may not be eager to report that fact. Neither will the campaign. Regarding fundraising, it’s hard enough for us to track down the human actors who are responsible for the “dark money” contributions controlling much of modern political finance; will we know if a future dominant force in fundraising for political action committees is an AI?

We’re likely to observe some of these milestones indirectly. At some point, perhaps politicians’ dollars will start migrating en masse to AI-based campaign consultancies and, eventually, we may realize that political movements sweeping across states or countries have been AI-assisted.

While the progression of technology is often unsettling, we need not fear these milestones. A new political platform that wins public support is itself a neutral proposition; it may lead to good or bad policy outcomes. Likewise, a successful policy program may or may not be beneficial to one group of constituents or another.

We think the six milestones outlined here are among the most viable and meaningful upcoming interactions between AI and democracy, but they are hardly the only scenarios to consider. The point is that our AI-driven political future will involve far more than deepfaked campaign ads and manufactured letter-writing campaigns. We should all be thinking more creatively about what comes next and be vigilant in steering our politics toward the best possible ends, no matter their means.

This essay was written with Nathan Sanders, and previously appeared in MIT Technology Review.

The Need for Trustworthy AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/08/the-need-for-trustworthy-ai.html

If you ask Alexa, Amazon’s voice assistant AI system, whether Amazon is a monopoly, it responds by saying it doesn’t know. It doesn’t take much to make it lambaste the other tech giants, but it’s silent about its own corporate parent’s misdeeds.

When Alexa responds in this way, it’s obvious that it is putting its developer’s interests ahead of yours. Usually, though, it’s not so obvious whom an AI system is serving. To avoid being exploited by these systems, people will need to learn to approach AI skeptically. That means deliberately constructing the input you give it and thinking critically about its output.

Newer generations of AI models, with their more sophisticated and less rote responses, are making it harder to tell who benefits when they speak. Internet companies’ manipulating what you see to serve their own interests is nothing new. Google’s search results and your Facebook feed are filled with paid entries. Facebook, TikTok and others manipulate your feeds to maximize the time you spend on the platform, which means more ad views, over your well-being.

What distinguishes AI systems from these other internet services is how interactive they are, and how these interactions will increasingly become like relationships. It doesn’t take much extrapolation from today’s technologies to envision AIs that will plan trips for you, negotiate on your behalf or act as therapists and life coaches.

They are likely to be with you 24/7, know you intimately, and be able to anticipate your needs. This kind of conversational interface to the vast network of services and resources on the web is within the capabilities of existing generative AIs like ChatGPT. They are on track to become personalized digital assistants.

As a security expert and data scientist, we believe that people who come to rely on these AIs will have to trust them implicitly to navigate daily life. That means they will need to be sure the AIs aren’t secretly working for someone else. Across the internet, devices and services that seem to work for you already secretly work against you. Smart TVs spy on you. Phone apps collect and sell your data. Many apps and websites manipulate you through dark patterns, design elements that deliberately mislead, coerce or deceive website visitors. This is surveillance capitalism, and AI is shaping up to be part of it.

Quite possibly, it could be much worse with AI. For that AI digital assistant to be truly useful, it will have to really know you. Better than your phone knows you. Better than Google search knows you. Better, perhaps, than your close friends, intimate partners and therapist know you.

You have no reason to trust today’s leading generative AI tools. Leave aside the hallucinations, the made-up “facts” that GPT and other large language models produce. We expect those will be largely cleaned up as the technology improves over the next few years.

But you don’t know how the AIs are configured: how they’ve been trained, what information they’ve been given, and what instructions they’ve been commanded to follow. For example, researchers uncovered the secret rules that govern the Microsoft Bing chatbot’s behavior. They’re largely benign but can change at any time.

Many of these AIs are created and trained at enormous expense by some of the largest tech monopolies. They’re being offered to people to use free of charge, or at very low cost. These companies will need to monetize them somehow. And, as with the rest of the internet, that somehow is likely to include surveillance and manipulation.

Imagine asking your chatbot to plan your next vacation. Did it choose a particular airline or hotel chain or restaurant because it was the best for you or because its maker got a kickback from the businesses? As with paid results in Google search, newsfeed ads on Facebook and paid placements on Amazon queries, these paid influences are likely to get more surreptitious over time.

If you’re asking your chatbot for political information, are the results skewed by the politics of the corporation that owns the chatbot? Or the candidate who paid it the most money? Or even the views of the demographic of the people whose data was used in training the model? Is your AI agent secretly a double agent? Right now, there is no way to know.

We believe that people should expect more from the technology and that tech companies and AIs can become more trustworthy. The European Union’s proposed AI Act takes some important steps, requiring transparency about the data used to train AI models, mitigation for potential bias, disclosure of foreseeable risks and reporting on industry standard tests.

Most existing AIs fail to comply with this emerging European mandate, and, despite recent prodding from Senate Majority Leader Chuck Schumer, the US is far behind on such regulation.

The AIs of the future should be trustworthy. Unless and until the government delivers robust consumer protections for AI products, people will be on their own to guess at the potential risks and biases of AI, and to mitigate their worst effects on people’s experiences with them.

So when you get a travel recommendation or political information from an AI tool, approach it with the same skeptical eye you would a billboard ad or a campaign volunteer. For all its technological wizardry, the AI tool may be little more than the same.

This essay was written with Nathan Sanders, and previously appeared on The Conversation.