Tag Archives: Advanced (300)

Build SAML identity federation for Amazon OpenSearch Service domains within a VPC

Post Syndicated from Mahdi Ebrahimi original https://aws.amazon.com/blogs/big-data/build-saml-identity-federation-for-amazon-opensearch-service-domains-within-a-vpc/

Amazon OpenSearch Service is a fully managed search and analytics service powered by the Apache Lucene search library that can be operated within a virtual private cloud (VPC). A VPC is a virtual network that’s dedicated to your AWS account. It’s logically isolated from other virtual networks in the AWS Cloud. Placing an OpenSearch Service domain within a VPC enables a secure communication between OpenSearch Service and other services within the VPC without the need for an internet gateway, NAT device, or a VPN connection. All traffic remains securely within the AWS Cloud, providing a safe environment for your data. To connect to an OpenSearch Service domain running inside a private VPC, enterprise customers use one of two available options: either integrate their VPC with their enterprise network through VPN or AWS Direct Connect, or make the cluster endpoint publicly accessible through a reverse proxy. Refer to How can I access OpenSearch Dashboards from outside of a VPC using Amazon Cognito authentication for a detailed evaluation of the available options and the corresponding pros and cons.

For managing access to OpenSearch Dashboards in enterprise customers’ environments, OpenSearch Service supports Security Assertion Markup Language (SAML) integration with the customer’s existing identity providers (IdPs) to offer single sign-on (SSO). Although SAML integration for publicly accessible OpenSearch Dashboards works out of the box, enabling SAML for OpenSearch Dashboards within a VPC requires careful design with various configurations.

This post outlines an end-to-end solution for integrating SAML authentication for OpenSearch Service domains running in a VPC. It provides a step-by-step deployment guideline and is accompanied by AWS Cloud Development Kit (AWS CDK) applications, which automate all the necessary configurations.

Overview of solution

The following diagram describes the step-by-step authentication flow for accessing a private OpenSearch Service domain through SSO using SAML identity federation. The access is enabled over public internet through private NGINX reverse proxy servers running on Amazon Elastic Container Service (Amazon ECS) for high availability.

Solution overview

The workflow consists of the following steps:

  1. The user navigates to the OpenSearch Dashboards URL in their browser.
  2. The browser resolves the domain IP address and sends the request.
  3. AWS WAF rules make sure that only allow listed IP address ranges are allowed.
  4. Application Load Balancer forwards the request to NGINX reverse proxy.
  5. NGINX adds the necessary headers and forwards the request to OpenSearch Dashboards.
  6. OpenSearch Dashboards detects that the request is not authenticated. It replies with a redirect to the integrated SAML IdP for authentication.
  7. The user is redirected to the SSO login page.
  8. The IdP verifies the user’s identity and generates a SAML assertion token.
  9. The user is redirected back to the OpenSearch Dashboards URL.
  10. The request goes through the Steps 1–5 again until it reaches OpenSearch. This time, OpenSearch Dashboards detects the accompanying SAML assertion and allows the request.

In the following sections, we set up a NGINX reverse proxy in private subnets to provide access to OpenSearch Dashboards for a domain deployed inside VPC private subnets. We then enable SAML authentication for OpenSearch Dashboards using a SAML 2.0 application and use a custom domain endpoint to access OpenSearch Dashboards to see the SAML authentication in action.

Prerequisites

Before you get started, complete the prerequisite steps in this section.

Install required tools

First, install the AWS CDK. For more information, refer to the AWS CDK v2 Developer Guide.

Prepare required AWS resources

Complete the following steps to set up your AWS resources:

  1. Create an AWS account.
  2. Create an Amazon Route 53 public hosted zone such as mydomain.com to be used for routing internet traffic to your domain. For instructions, refer to Creating a public hosted zone.
  3. Request an AWS Certificate Manager (ACM) public certificate for the hosted zone. For instructions, refer to Requesting a public certificate.
  4. Create a VPC with public and private subnets.
  5. Enable AWS IAM Identity Center. For instructions, refer to Enable IAM Identity Center.

Prepare your OpenSearch Service cluster

This post is accompanied with a standalone AWS CDK application (opensearch-domain) that deploys a sample OpenSearch Service domain in private VPC subnets. The deployed domain is for demonstration purposes only, and is optional.

If you have an existing OpenSearch Service domain in VPC that you want to use for SAML integration, apply the following configurations:

  1. On the Cluster configuration tab, choose Edit and select Enable custom endpoint in the Custom endpoint section.
  2. For Custom hostname, enter a fully qualified domain name (FQDN) such as opensearch.mydomain.com, which you want to use to access your cluster. Note that the domain name of the provided FQDN (for example, mydomain.com) must be the same as the public hosted zone you created earlier.
  3. For AWS certificate, choose the SSL certificate you created earlier.
  4. In the Summary section, optionally enable dry run analysis and select Dry run or deselect it and choose Save changes.

Otherwise, download the accompanied opensearch-domain AWS CDK application and unzip it. Then, edit the cdk.json file on the root of the unzipped folder and configure the required parameters:

  • vpc_cidr – The CIDR block in which to create the VPC. You may leave the default of 10.0.0.0/16.
  • opensearch_cluster_name – The name of the OpenSearch Service cluster. You may leave the default value of opensearch. It will also be used, together with the hosted_zone_name parameter, to build the FQDN of the custom domain URL.
  • hosted_zone_id – The Route 53 public hosted zone ID.
  • hosted_zone_name – The Route 53 public hosted zone name (for example, mydomain.com). The result FQDN with the default example values will then be opensearch.mydomain.com.

Finally, run the following commands to deploy the AWS CDK application:

cd opensearch-domain

# Create a Python environment and install the reuired dependencies
python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements-dev.txt
pip install -r requirements.txt

# Deploy the CDK application
cdk deploy

With the prerequisites in place, refer to the following sections for a step-by-step guide to deploy this solution.

Create a SAML 2.0 application

We use IAM Identity Center as the source of identity for our SAML integration. The same configuration should apply to other SAML 2.0-compliant IdPs. Consult your IdP documentation.

  1. On the IAM Identity Center console, choose Groups in the navigation pane.
  2. Create a new group called Opensearch Admin, and add users to it.
    This will be the SAML group that receives full permissions in OpenSearch Dashboards. Take note of the group ID.OpenSearch Admin Group
  3. Choose Applications in the navigation pane.
  4. Create a new custom SAML 2.0 application.Create SAML application
  5. Download the IAM Identity Center SAML metadata file to use in a later step.IAM Identity Center SAML metadata
  6. For Application start URL, enter [Custom Domain URL]/_dashboards/.
    The custom domain URL is composed of communication protocol (https://) followed by the FQDN, which you used for your OpenSearch Service cluster in the prerequisites (for example, https://opensearch.mydomain.com). Look under your OpenSearch Service cluster configurations, if in doubt.
  7. For Application ACS URL, enter [Custom Domain URL]/_dashboards/_opendistro/_security/saml/acs.
  8. For Application SAML audience, enter [Custom Domain URL] (without any trailing slash).
    OpenSearch domain SAML properties
  9. Choose Submit.
  10. In the Assigned users section, select Opensearch Admin and choose Assign Users.Assign admin group to SAML application
  11. On the Actions menu, choose Edit attribute mappings.Edit SAML application's attribute mapping
  12. Define attribute mappings as shown in the following screenshot and choose Save changes.Configure SAML application's attribute mappings

Deploy the AWS CDK application

Complete the following steps to deploy the AWS CDK application:

  1. Download and unzip the opensearch-domain-saml-integration AWS CDK application.
  2. Add your private SSL key and certificate to AWS Secrets Manager and create two secrets called Key and Crt. For example, see the following code:
    KEY=$(cat private.key | base64) && aws secretsmanager create-secret --name Key --secret-string $KEY
    CRT=$(cat certificate.crt | base64) && aws secretsmanager create-secret --name Crt --secret-string $CRT

    You can use the following command to generate a self-signed certificate. This is for testing only; do not use this for production environments.

    openssl req -new -newkey rsa:4096 -days 1095 -nodes -x509 -subj '/' -keyout private.key -out certificate.crt

  3. Edit the cdk.json file and set the required parameters inside the nested config object:
  • aws_region – The target AWS Region for your deployment (for example, eu-central-1).
  • vpc_id – The ID of the VPC into which the OpenSearch Service domain has been deployed.
  • opensearch_cluster_security_group_id – The ID of the security group used by the OpenSearch Service domain or any other security group that allows inbound connections to that domain on port 80 and 443. This group ID will be used by the Application Load Balancer to forward traffic to your OpenSearch Service domain.
  • hosted_zone_id – The Route 53 public hosted zone ID.
  • hosted_zone – The Route 53 public hosted zone name (for example, mydomain.com).
  • opensearch_custom_domain_name – An FQDN such as opensearch.mydomain.com, which you want to use to access your cluster. Note that the domain name of the provided FQDN (mydomain.com) must be the same as the hosted_zone parameter.
  • opensearch_custom_domain_certificate_arn – The ARN of the certificate stored in ACM.
  • opensearch_domain_endpoint – The OpenSearch Service VPC domain endpoint (for example, vpc-opensearch-abc123.eu-central-1.es.amazonaws.com).
  • vpc_dns_resolver – This must be 10.0.0. if your VPC CIDR is 10.0.0.0/16. See Amazon DNS server for further details.
  • alb_waf_ip_whitelist_cidrs – This is an optional list of zero or more IP CIDR ranges that will be automatically allow listed in AWS WAF to permit access to the OpenSearch Service domain. If not specified, after the deployment you will need to manually add relevant IP CIDR ranges to the AWS WAF IP set to allow access. For example, ["1.2.3.4/32", "5.6.7.0/24"].
  1. Deploy the OpenSearch Service domain SAML integration AWS CDK application:
    cd opensearch-domain-saml-integration
    
    # Create a Python environment and install the required dependencies
    python3 -m venv .venv
    source .venv/bin/activate
    pip install -r requirements-dev.txt
    pip install -r requirements.txt
    
    # Deploy the CDK application
    cdk deploy

Enable SAML authentication for your OpenSearch Service cluster

When the application deployment is complete, enable SAML authentication for your cluster:

  1. On the OpenSearch Service console, navigate to your domain.
  2. On the Security configuration tab, choose Edit.Enable SAML authentication for OpenSearch domain
  3. Select Enable SAML authentication.
  4. Choose Import from XML file and import the IAM Identity Center SAML metadata file that you downloaded in an earlier step.
  5. For SAML master backend role, use the group ID you saved earlier.
  6. Expand the Additional settings section and for Roles, enter the SAML 2.0 attribute name you mapped earlier when you created the SAML 2.0 application in AWS Identity Center.
  7. Configure the domain access policy for SAML integration.
  8. Submit changes and wait for OpenSearch Service to apply the configurations before proceeding to the next section.

Test the solution

Complete the following steps to see the solution in action:

  1. On the IAM Identity Center console, choose Dashboard in the navigation pane.
  2. In the Settings summary section, choose the link under AWS access portal URL.Login to IAM Identity Centre
  3. Sign in with your user name and password (register your password if this is your first login).
    If your account was successfully added to the admin group, a SAML application logo is visible.
  4. Choose Custom SAML 2.0 application to be redirected to the OpenSearch Service dashboards through SSO without any additional login attempts.Open SAML application
    Alternatively, you could skip logging in to the access portal and directly point your browser to the OpenSearch Dashboards URL. In that case, OpenSearch Dashboards would first redirect you to the access portal to log in, which would redirect you back to the OpenSearch Dashboards UI after a successful login, resulting in the same outcome as shown in the following screenshot.OpenSearch Dashboards UI after successful login

Troubleshooting

Your public-facing IP must be allow listed by the AWS WAF rule, otherwise a 403 Forbidden error will be returned. Allow list your IP CIDR range via the AWS CDK alb_waf_ip_whitelist_cidrs property as described in the installation guide and redeploy the AWS CDK application for changes to take effect.

Clean up

When you’re finished with this configuration, clean up the resources to avoid future charges.

  1. On the OpenSearch Service console, navigate to the Security configuration tab of your OpenSearch Service domain and choose Edit.
  2. Deselect Enable SAML authentication and choose Save changes.
  3. After the Amazon SAML integration is disabled, delete the opensearch-domain-saml-integration stack using cdk destroy.
  4. Optionally, if you used the provided OpenSearch Service sample AWS CDK stack (opensearch-domain), delete it using cdk destroy.

Conclusion

OpenSearch Service allows enterprise customers to use their preferred federated IdPs such as SAML using IAM Identity Center for clusters running inside private VPC subnets following AWS best practices.

In this post, we showed you how to integrate an OpenSearch Service domain within a VPC with an existing SAML IdP for SSO access to OpenSearch Dashboards using IAM Identity Center. The provided solution securely manages network access to the resources using AWS WAF to restrict access only to authorized network segments or specific IP addresses.

To get started, refer to How can I access OpenSearch Dashboards from outside of a VPC using Amazon Cognito authentication for further comparison of OpenSearch Service domain in private VPC access patterns.


About the Authors

Mahdi Ebrahimi is a Senior Cloud Infrastructure Architect with Amazon Web Services. He excels in designing distributed, highly-available software systems. Mahdi is dedicated to delivering cutting-edge solutions that empower his customers to innovate in the rapidly evolving landscape in the automotive industry.

Dmytro Protsiv is a Cloud Applications Architect for with Amazon Web Services. He is passionate about helping customers to solve their business challenges around application modernization.

Luca Menichetti is a Big Data Architect with Amazon Web Services. He helps customers develop performant and reusable solutions to process data at scale. Luca is passioned about managing organisation’s data architecture, enabling data analytics and machine learning. Having worked around the Hadoop ecosystem for a decade, he really enjoys tackling problems in NoSQL environments.

Krithivasan Balasubramaniyan is a Principal Consultant with Amazon Web Services. He enables global enterprise customers in their digital transformation journey and helps architect cloud native solutions.

Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

How to migrate asymmetric keys from CloudHSM to AWS KMS

Post Syndicated from Mani Manasa Mylavarapu original https://aws.amazon.com/blogs/security/how-to-migrate-asymmetric-keys-from-cloudhsm-to-aws-kms/

In June 2023, Amazon Web Services (AWS) introduced a new capability to AWS Key Management Service (AWS KMS): you can now import asymmetric key materials such as RSA or elliptic-curve cryptography (ECC) private keys for your signing workflow into AWS KMS. This means that you can move your asymmetric keys that are managed outside of AWS KMS—such as a hybrid (on-premises) environment, multi-cloud environment, and even AWS CloudHSM—and make them available through AWS KMS. Combined with the announcement on AWS KMS HSMs achieving FIPS 140-2 Security Level 3, you can make sure that your keys are secured and used in a manner that aligns to the cryptographic standards laid out by the U.S. National Institute of Standards and Technology (NIST).

In this post, we will show you how to migrate your asymmetric keys from CloudHSM to AWS KMS. This can help you simplify your key management strategy and take advantage of the robust authorization control of AWS KMS key policies.

Benefits of importing key materials into AWS KMS

In general, we recommend that you use a native KMS key because it provides the best security, durability, and availability compared to other key store options. AWS KMS FIPS-validated hardware security modules (HSMs) generate the key materials for KMS keys, and these key materials never leave the HSMs unencrypted. Operations that require use of your KMS key (for example, decryption of a data key or digital signature signing) must occur within the HSM.

However, depending on your organization’s requirements, you might need to bring your own key (BYOK) from outside. Importing your own key gives you direct control over the generation, lifecycle management, and durability of your keys. In addition, you have full control over the availability of your imported keys because you can set an expiration period or delete and reimport the keys at any time. You have greater control over the durability of your imported keys because you can maintain the original version of the keys elsewhere. If you need to generate and store copies of keys outside of AWS, these additional controls can help you meet your compliance requirements.

Solution overview

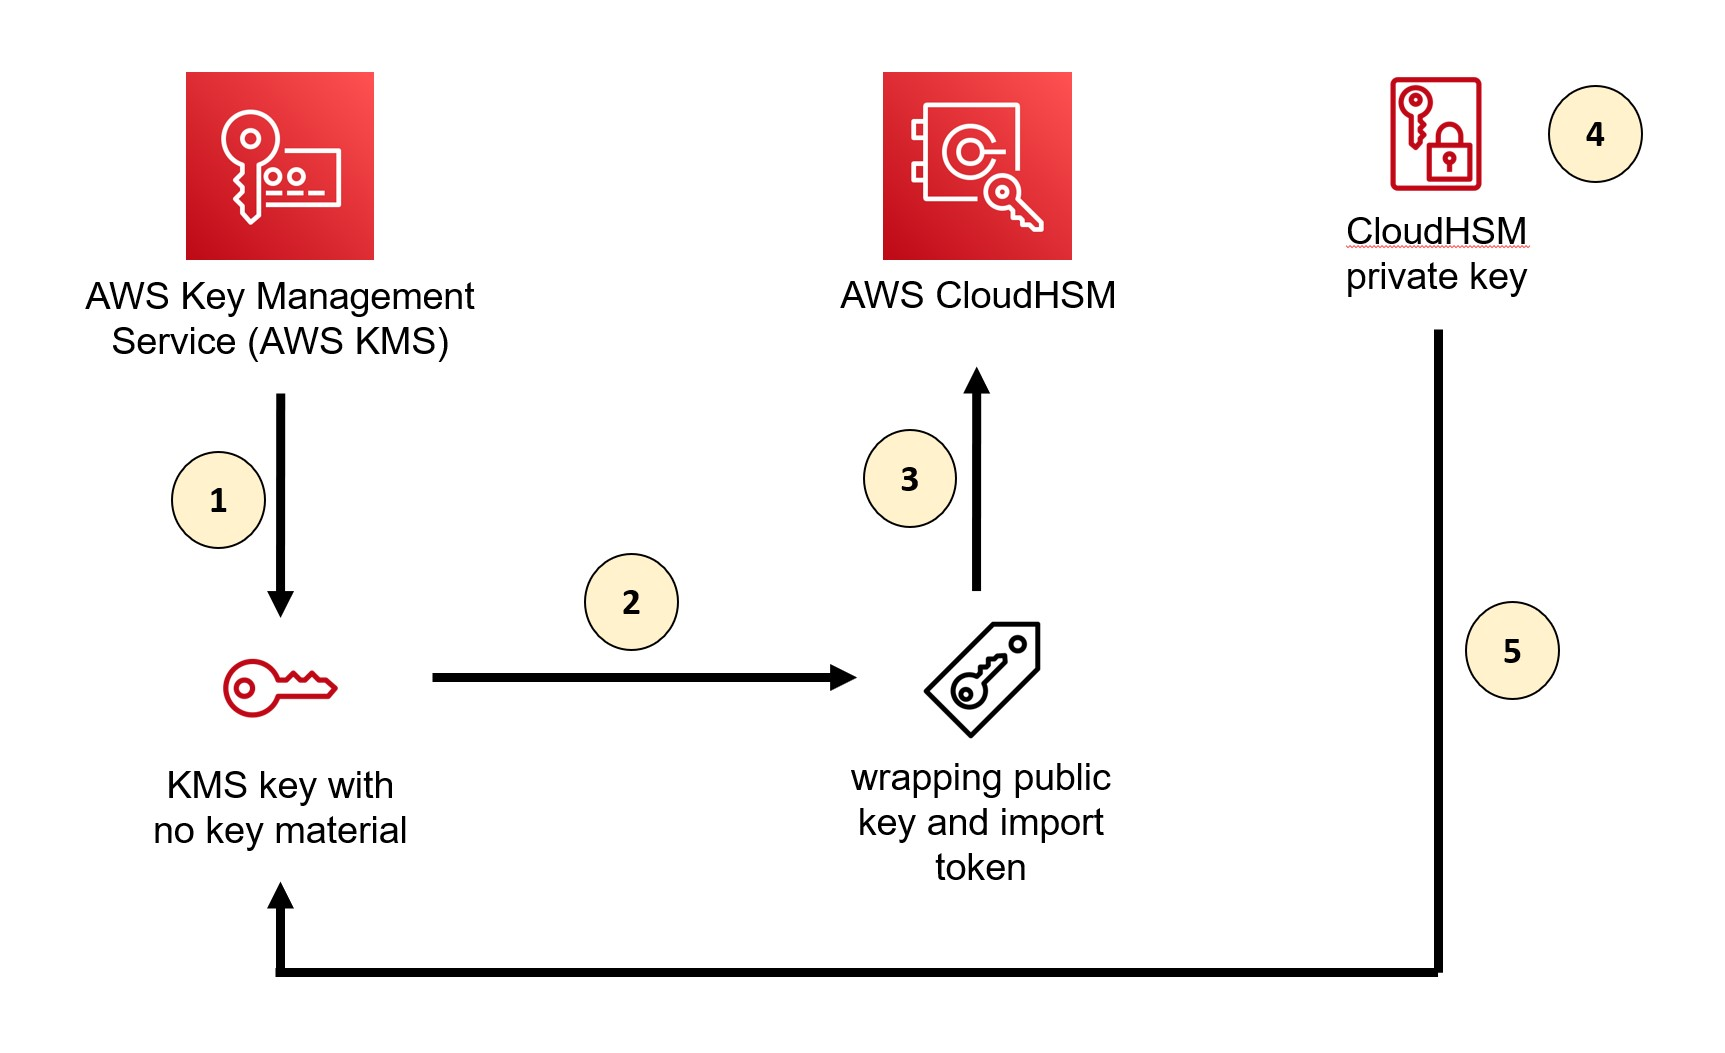
At a high level, our solution involves downloading the wrapping key from AWS KMS, using the CloudHSM Command Line Interface (CLI) to import a wrapping key to CloudHSM, wrapping the private key by using the wrapping key in CloudHSM, and uploading the wrapped private key to AWS KMS by using an import token. You can perform the same procedures by using other supported libraries, such as the PKCS #11 library or a JCE provider.

Figure 1: Overall architecture of the solution

Figure 1: Overall architecture of the solution

As shown in Figure 1, the solution involves the following steps:

  1. Create a KMS key without key material in AWS KMS
  2. Download the wrapping public key and import token from AWS KMS
  3. Import the wrapping key provided by AWS KMS into CloudHSM
  4. Wrap the private key inside CloudHSM with the imported wrapping public key from AWS KMS
  5. Import the wrapped private key to AWS KMS

For the walkthrough in this post, you will import into AWS KMS an ECC 256-bit private key (NIST P-256) that’s used for signing purpose from a CloudHSM cluster. When you import an asymmetric key into AWS KMS, you only need to import a private key. You don’t need to import a public key because AWS KMS can generate and retrieve a public key from the private key after the private key is imported.

Prerequisites

To follow along with this walkthrough, make sure that you have the following prerequisites in place:

  1. An active CloudHSM cluster with at least one active HSM and a valid crypto user credential.
  2. An Amazon Elastic Compute Cloud (Amazon EC2) instance with the CloudHSM Client SDK 5 installed and configured to connect to the CloudHSM cluster. For instructions on how to configure and connect the client instance, see Getting started with AWS CloudHSM.
  3. OpenSSL installed on your EC2 instance (we recommend version 3.0.0 or newer).

Step 1: Create a KMS key without key material in AWS KMS

The first step is to create a new KMS key. You can do this through the AWS KMS console or the AWS CLI, or by running the CreateKey API operation.

When you create your key, keep the following guidance in mind:

  • Set the key material origin to External so that no key material is created for this new key.
  • According to NIST SP 800-57 guidance and cryptography best practice, in general, you should use a single key for only one purpose (for example, if you use an RSA key for encryption, you shouldn’t also use that key for signing). Select the key usage that best suits your use case.
  • Make sure that the key spec match the algorithm specification of the key that you are trying to import from CloudHSM.
  • If you want to use the key in multiple AWS Regions (for example, to avoid the need for a cross-Region call to access the key), consider using a multi-Region key.

To create a KMS key using the AWS CLI

  • Run the following command:
    aws kms create-key --origin EXTERNAL --key-spec ECC_NIST_P256 --key-usage SIGN_VERIFY

Step 2: Download the wrapping public key and import token from AWS KMS

After you create the key, download the wrapping key and import token.

The wrapping key spec and the wrapping algorithm that you select depend on the key that you’re trying to import. AWS KMS supports several standard RSA wrapping algorithms and a two-step hybrid wrapping algorithm. CloudHSM supports both wrapping algorithms as well.

In general, an RSA wrapping algorithm (RSAES_OAEP_SHA_*) with a key spec of RSA_4096 should be sufficient for wrapping ECC private keys because it can wrap the key material completely. However, when importing RSA private keys, you will need to use the two-step hybrid wrapping algorithm (RSA_AES_KEY_WRAP_SHA_*) due to their large key size. The overall process is the same as what’s shown here, but the two-step hybrid wrapping algorithm requires that you encrypt your key material with an Advanced Encryption Standard (AES) symmetric key that you generate, and then encrypt the AES symmetric key with the RSA public wrapping key. Additionally, when you select the wrapping algorithm, you also have a choice between the SHA-1 or SHA-256 hashing algorithm. We recommend that you use the SHA-256 hashing algorithm whenever possible.

Note that each wrapping public key and import token set is valid for 24 hours. If you don’t use the set to import key material within 24 hours of downloading it, you must download a new set.

To download the wrapping public key and import token from AWS KMS

  1. Run the following command. Make sure to replace <KMS KeyID> with the key ID of the KMS key that you created in the previous step. The key ID is the last part of the key ARN after :key/ (for example, arn:aws:kms:us-east-1:<AWS Account ID>:key/<Key ID>). “ImportToken.b64” represents the wrapping token, and “WrappingPublicKey.b64” represents the import token.
    aws kms get-parameters-for-import \
    --key-id <KMS KeyID> \
    --wrapping-algorithm RSAES_OAEP_SHA_256 \
    --wrapping-key-spec RSA_4096 \
    --query "[ImportToken, PublicKey]" \
    --output text \
    | awk '{print $1 > "ImportToken.b64"; print $2 > "WrappingPublicKey.b64"}'

  2. Decode the base64 encoding.
    openssl enc -d -base64 -A -in WrappingPublicKey.b64 -out WrappingPublicKey.bin

To convert the wrapping public key from DER to PEM format

  • The key import pem command in CloudHSM CLI requires that the public key is in PEM format. AWS KMS outputs public keys in the DER format, so you must convert the wrapping public key to PEM format. To convert the public key to PEM format, run the following command:
    openssl rsa -pubin -in WrappingPublicKey.bin -inform DER -outform PEM -out WrappingPublicKey.pem

Step 3: Import the wrapping key provided by AWS KMS into CloudHSM

Now that you have created the KMS key and made the necessary preparations to import it, switch to CloudHSM to import the key.

To import the wrapping key

  1. Log in to your EC2 instance that has the CloudHSM CLI installed and run the following command to use it in an interactive mode:
    /opt/cloudhsm/bin/cloudhsm-cli interactive

  2. Log in with your crypto user credential. Make sure to replace <YourUserName> with your own information and supply your password when prompted.
    login --username <YourUserName> --role crypto-user

  3. Import the wrapping key and set the attribute allowing this key to be used for wrapping other keys.
    key import pem --path ./WrappingPublicKey.pem --label <kms-wrapping-key> --key-type-class rsa-public --attributes wrap=true

    You should see an output similar to the following:

    {
      "error_code": 0,
      "data": {
        "key": {
          "key-reference": "0x00000000002800c2",
          "key-info": {
            "key-owners": [
              {
                "username": "<YourUserName>",
                "key-coverage": "full"
              }
            ],
            "shared-users": [],
            "cluster-coverage": "full"
          },
          "attributes": {
            "key-type": "rsa",
            "label": "<kms-wrapping-key>",
            "id": "0x",
            "check-value": "0x5efd07",
            "class": "public-key",
            "encrypt": false,
            "decrypt": false,
            "token": true,
            "always-sensitive": false,
            "derive": false,
            "destroyable": true,
            "extractable": true,
            "local": false,
            "modifiable": true,
            "never-extractable": false,
            "private": true,
            "sensitive": false,
            "sign": false,
            "trusted": false,
            "unwrap": false,
            "verify": false,
            "wrap": true,
            "wrap-with-trusted": false,
            "key-length-bytes": 1024,
            "public-exponent": "0x010001",
            "modulus": "0xd7683010 … b6fc9df07",
            "modulus-size-bits": 4096
          }
        },
        "message": "Successfully imported key"
      }
    }

  4. From the output, note the value for the key label (<kms-wrapping-key> in this example) because you will need it for the next step.

Step 4: Wrap the private key inside CloudHSM with the imported wrapping public key from AWS KMS

Now that you have imported the wrapping key into CloudHSM, you can wrap the private key that you want to import to AWS KMS by using the wrapping key.

Important: Only the owner of a key—the crypto user who created the key—can wrap the key. In addition, the key that you want to wrap must have the extractable attribute set to true.

To wrap the private key

  1. Use the key wrap command in the CloudHSM CLI to wrap the private key that’s stored in CloudHSM. Make sure to replace the following placeholder values with your own information:
    • rsa-oaep specifies the wrapping algorithm.
    • --payload-filter is used to define the key that you want to wrap out of the HSM. You can use the key reference (for example, key-reference=0x00000000002800c2) or reference key attributes, such as the key label. In our example, we used the key label ec-priv-import-to-kms.
    • --wrapping-filter is used to define the key that you will use to wrap out the payload key. This should be the wrapping key that you imported previously from AWS KMS, which was labeled kms-wrapping-key in Step 3.3.
    • --hash-function defines the hash function used as part of the OAEP encryption. This should match the wrapping algorithm that you specified when you got the import parameters from AWS KMS. In our example, it should be SHA-256 because we selected RSAES_OAEP_SHA_256 as the wrapping algorithm previously.
    • --mgf defines the mask generation function used as part of the OAEP encryption. The mask hash function must match the signing mechanism hash function, which is SHA-256 in this example.
    • --path defines the path to the binary file where the wrapped key data will be saved. In this example, we name the file EncryptedECC_P256KeyMaterial.bin but you can specify a different name.
    key wrap rsa-oaep --payload-filter attr.label=ec-priv-import-to-kms --wrapping-filter attr.label=kms-wrapping-key --hash-function sha256 --mgf mgf1-sha256 --path EncryptedECC_P256KeyMaterial.bin

(Optional) To export the public key

  • You can also use the CloudHSM CLI to export the public key of your private key. You will use this key for testing later. Make sure to replace the placeholder values <ec-priv-import-to-kms> and <KeyName.pem> with your own information.
    key generate-file --encoding pem --path <KeyName.pem> --filter attr.label=<ec-priv-import-to-kms>

Step 5: Import the wrapped private key to AWS KMS

Now that you’ve wrapped the private key from CloudHSM, you can import it into AWS KMS.

Note that you have the option to set an expiration time for your imported key. After the expiration time passes, AWS KMS deletes your imported key automatically.

To import the wrapped private key to AWS KMS

  1. If you have been using the CLI or API, the import token is base64 encoded. You must decode the token from base64 to binary format before it can be used. You can use OpenSSL to do this.
    openssl enc -d -base64 -A -in ImportToken.b64 -out ImportToken.bin

  2. Run the following command to import the wrapped private key. Make sure to replace <KMS KeyID> with the key ID of the KMS key that you created in Step 1.
    aws kms import-key-material --key-id <KMS KeyID> \
    --encrypted-key-material fileb://EncryptedECC_P256KeyMaterial.bin \
    --import-token fileb://ImportToken.bin \
    --expiration-model KEY_MATERIAL_DOES_NOT_EXPIRE

Test whether your private key was imported successfully

The nature of asymmetric cryptography means that a digital signature produced by your private key should produce the same signature on the same message, regardless of the tool that you used to perform the signing operation. To verify that your imported private key functions the same in both CloudHSM and AWS KMS, you can perform a signing operation and compare the signature on CloudHSM and AWS KMS to make sure that they are the same.

Another way to check that your imported private key functions are the same in AWS KMS is to perform a signing operation and then verify the signature by using the corresponding public key that you exported from CloudHSM in Step 4. We will show you how to use this method to check that your private key was imported successfully.

To test that your private key was imported

  1. Create a simple message in a text file and encode it in base64.
    echo -n 'Testing My Imported Key!' | openssl base64 -out msg_base64.txt

  2. Perform the signing operation by using AWS KMS. Make sure to replace <YourImported KMS KeyID> with your own information.
    aws kms sign --key-id <YourImported KMS KeyID> --message fileb://msg_base64.txt --message-type RAW --signing-algorithm ECDSA_SHA_256

    The following shows the output of the signing operation.

    {
    "KeyId": "arn:aws:kms:us-east-1:111122223333:key/1234abcd-12ab-34cd-56ef-1234567890ab",
    "Signature": "EXAMPLEXsP11QVTkrSsab2CygcgtodDbSpd+j558B4qINpKIxwIhAMkKwd65mA3roo76ItuHiRsbwO9F0XMyuyKCKEXAMPLE",
    "SigningAlgorithm": "ECDSA_SHA_256"
    }

  3. Save the signature in a separate file called signature.sig and decode it from base64 to binary.
    openssl enc -d -base64 -in signature.sig -out signature.bin

  4. Verify the signature by using the public key that you exported from CloudHSM in Step 4.
    openssl dgst -sha256 -verify <KeyName.pem> -signature signature.bin msg_base64.txt

    If successful, you should see a message that says Verified OK.

Conclusion

In this post, you learned how to import an asymmetric key into AWS KMS from CloudHSM by using the CloudHSM CLI.

Although this post focused on migrating keys from CloudHSM, you can also follow the general directions to import your asymmetric key from elsewhere. When you import a private key, make sure that the imported key matches the key spec and the wrapping algorithm that you choose in AWS KMS.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Mani Manasa Mylavarapu

Mani Manasa Mylavarapu

Manasa is a Software Development Manager at AWS KMS. Manasa leads the development of custom key store features for both the CloudHSM Key Store and External Key Store. Beyond her professional role, Manasa enjoys playing board games and exploring the scenic hikes of Seattle.

Author

Kevin Lee

Kevin is a Senior Product Manager at AWS KMS. Kevin’s work interests include client-side encryption and key management strategy within a multi-tenant environment. Outside of work, Kevin enjoys occasional camping and snowboarding in the Pacific Northwest and playing video games.

Patrick Palmer

Patrick Palmer

Patrick is a Principal Security Specialist Solutions Architect. He helps customers around the world use AWS services in a secure manner, and specializes in cryptography. When not working, he enjoys spending time with his growing family and playing video games.

Preprocess and fine-tune LLMs quickly and cost-effectively using Amazon EMR Serverless and Amazon SageMaker

Post Syndicated from Shijian Tang original https://aws.amazon.com/blogs/big-data/preprocess-and-fine-tune-llms-quickly-and-cost-effectively-using-amazon-emr-serverless-and-amazon-sagemaker/

Large language models (LLMs) are becoming increasing popular, with new use cases constantly being explored. In general, you can build applications powered by LLMs by incorporating prompt engineering into your code. However, there are cases where prompting an existing LLM falls short. This is where model fine-tuning can help. Prompt engineering is about guiding the model’s output by crafting input prompts, whereas fine-tuning is about training the model on custom datasets to make it better suited for specific tasks or domains.

Before you can fine-tune a model, you need to find a task-specific dataset. One dataset that is commonly used is the Common Crawl dataset. The Common Crawl corpus contains petabytes of data, regularly collected since 2008, and contains raw webpage data, metadata extracts, and text extracts. In addition to determining which dataset should be used, cleansing and processing the data to the fine-tuning’s specific need is required.

We recently worked with a customer who wanted to preprocess a subset of the latest Common Crawl dataset and then fine-tune their LLM with cleaned data. The customer was looking for how they could achieve this in the most cost-effective way on AWS. After discussing the requirements, we recommended using Amazon EMR Serverless as their platform for data preprocessing. EMR Serverless is well suited for large-scale data processing and eliminates the need for infrastructure maintenance. In terms of cost, it only charges based on the resources and duration used for each job. The customer was able to preprocess hundreds of TBs of data within a week using EMR Serverless. After they preprocessed the data, they used Amazon SageMaker to fine-tune the LLM.

In this post, we walk you through the customer’s use case and architecture used.

Solution overview

In the following sections, we first introduce the Common Crawl dataset and how to explore and filter the data we need. Amazon Athena only charges for the data size it scans and is used to explore and filter the data quickly, while being cost-effective. EMR Serverless provides a cost-efficient and no-maintenance option for Spark data processing, and is used to process the filtered data. Next, we use Amazon SageMaker JumpStart to fine-tune the Llama 2 model with the preprocessed dataset. SageMaker JumpStart provides a set of solutions for the most common use cases that can be deployed with just a few clicks. You don’t need to write any code to fine-tune an LLM such as Llama 2. Finally, we deploy the fine-tuned model using Amazon SageMaker and compare the differences in text output for the same question between the original and fine-tuned Llama 2 models.

The following diagram illustrates the architecture of this solution.

Prerequisites

Before you dive deep into the solution details, complete the following prerequisite steps:

  1. Create an Amazon Simple Storage Service (Amazon S3) bucket to store the cleaned dataset. For instructions, refer to Create your first S3 bucket.
  2. Set up Athena to run interactive SQL.
  3. Create an EMR Serverless environment.
  4. Prepare Amazon SageMaker Studio to fine-tune your LLM and run Jupyter notebooks. For instructions, refer to Get started.

The Common Crawl dataset

Common Crawl is an open corpus dataset obtained by crawling over 50 billion webpages. It includes massive amounts of unstructured data in multiple languages, starting from 2008 and reaching the petabyte level. It is continuously updated.

In the training of GPT-3, the Common Crawl dataset accounts for 60% of its training data, as shown in the following diagram (source: Language Models are Few-Shot Learners).

Another important dataset worth mentioning is the C4 dataset. C4, short for Colossal Clean Crawled Corpus, is a dataset derived from postprocessing the Common Crawl dataset. In Meta’s LLaMA paper, they outlined the datasets used, with Common Crawl accounting for 67% (utilizing 3.3 TB of data) and C4 for 15% (utilizing 783 GB of data). The paper emphasizes the significance of incorporating differently preprocessed data for enhancing model performance. Despite the original C4 data being part of Common Crawl, Meta opted for the reprocessed version of this data.

In this section, we cover common ways to interact, filter, and process the Common Crawl dataset.

Common Crawl data

The Common Crawl raw dataset includes three types of data files: raw webpage data (WARC), metadata (WAT), and text extraction (WET).

Data collected after 2013 is stored in WARC format and includes corresponding metadata (WAT) and text extraction data (WET). The dataset is located in Amazon S3, updated on a monthly basis, and can be accessed directly through AWS Marketplace.

For example, the following snippet is data from June of 2023:

$  aws s3 ls s3://commoncrawl/crawl-data/CC-MAIN-2023-23/
PRE segments/
2023-06-21  00:34:08       2164  cc-index-table.paths.gz
2023-06-21  00:34:08        637 cc-index.paths.gz
2023-06-21  05:52:05       2724 index.html
2023-06-21  00:34:09     161064  non200responses.paths.gz
2023-06-21  00:34:10     160888 robotstxt.paths.gz
2023-06-21  00:34:10        480 segment.paths.gz
2023-06-21  00:34:11     161082 warc.paths.gz
2023-06-21  00:34:12     160895 wat.paths.gz
2023-06-21  00:34:12     160898 wet.paths.gz

cc-index-table

The Common Crawl dataset also provides an index table for filtering data, which is called cc-index-table.

The cc-index-table is an index of the existing data, providing a table-based index of WARC files. It allows for easy lookup of information, such as which WARC file corresponds to a specific URL.

The Common Crawl GitHub repo provides corresponding Athena statements to query the index. For explanations of each field, refer to Common Crawl Index Athena.

For example, you can create an Athena table to map cc-index data with the following code:

CREATE  EXTERNAL TABLE IF NOT EXISTS ccindex (
  url_surtkey                   STRING,
  url                           STRING,
  url_host_name                 STRING,
  url_host_tld                  STRING,
  url_host_2nd_last_part        STRING,
  url_host_3rd_last_part        STRING,
  url_host_4th_last_part        STRING,
  url_host_5th_last_part        STRING,
  url_host_registry_suffix      STRING,
  url_host_registered_domain    STRING,
  url_host_private_suffix       STRING,
  url_host_private_domain       STRING,
  url_host_name_reversed        STRING,
  url_protocol                  STRING,
  url_port                      INT,
  url_path                      STRING,
  url_query                     STRING,
  fetch_time                    TIMESTAMP,
  fetch_status                  SMALLINT,
  fetch_redirect                STRING,
  content_digest                STRING,
  content_mime_type             STRING,
  content_mime_detected         STRING,
  content_charset               STRING,
  content_languages             STRING,
  content_truncated             STRING,
  warc_filename                 STRING,
  warc_record_offset            INT,
  warc_record_length            INT,
  warc_segment                  STRING)
PARTITIONED  BY (
  crawl                         STRING,
  subset                        STRING)
STORED  AS parquet
LOCATION  's3://commoncrawl/cc-index/table/cc-main/warc/';
 
# add partitions
MSCK  REPAIR TABLE ccindex

# query
select  * from ccindex 
where  crawl = 'CC-MAIN-2018-05' 
  and  subset = 'warc' 
  and  url_host_tld = 'no' 
limit  10

The preceding SQL statements demonstrate how to create an Athena table, add partitions, and run a query.

Filter data from the Common Crawl dataset

As you can see from the create table SQL statement, there are several fields that can help filter the data. For example, if you want to get the count of Chinese documents during a specific period, then the SQL statement could be as follows:

SELECT
  url,
  warc_filename,
  content_languages
FROM  ccindex
WHERE  (crawl = 'CC-MAIN-2023-14'
  OR crawl = 'CC-MAIN-2023-23')
  AND subset = 'warc'
  AND content_languages ='zho'
LIMIT  10000

If you want to do further processing, you can save the results to another S3 bucket.

Analyze the filtered data

The Common Crawl GitHub repository provides several PySpark examples for processing the raw data.

Let’s look at an example of running server_count.py (example script provided by the Common Crawl GitHub repo) on the data located in s3://commoncrawl/crawl-data/CC-MAIN-2023-23/segments/1685224643388.45/warc/.

First, you need a Spark environment, such as EMR Spark. For example, you can launch an Amazon EMR on EC2 cluster in us-east-1 (because the dataset is in us-east-1). Using an EMR on EC2 cluster can help you carry out tests before submitting jobs to the production environment.

After launching an EMR on EC2 cluster, you need to do an SSH login to the primary node of the cluster. Then, package the Python environment and submit the script (refer to the Conda documentation to install Miniconda):

#  create conda environment
conda  create -y -n example -c dmnapolitano python=3.7 botocore boto3 ujson requests  conda-pack warcio

#  package the conda env
conda  activate example
conda  pack -o environment.tar.gz

#  get script from common crawl github
git  clone https://github.com/commoncrawl/cc-pyspark.git

#  copy target file path to local
aws  s3 cp s3://commoncrawl/crawl-data/CC-MAIN-2023-23/warc.paths.gz .
gzip  -d warc.paths.gz

#  put warc list to hdfs
hdfs  dfs -put warc.paths

#  submit job
spark-submit  --conf spark.yarn.appMasterEnv.PYSPARK_PYTHON=./environment/bin/python \
--conf spark.sql.warehouse.dir=s3://xxxx-common-crawl/output/  \
--master yarn \ 
--deploy-mode cluster \
--archives environment.tar.gz#environment \
--py-files cc-pyspark/sparkcc.py  cc-pyspark/server_count.py --input_base_url  s3://commoncrawl/ ./warc.paths count_demo

It can take time to process all references in the warc.path. For demo purposes, you can improve the processing time with the following strategies:

  • Download the file s3://commoncrawl/crawl-data/CC-MAIN-2023-23/warc.paths.gz to your local machine, unzip it, and then upload it to HDFS or Amazon S3. This is because the .gzip file is not splitable. You need to unzip it to process this file in parallel.
  • Modify the warc.path file, delete most of its lines, and only keep two lines to make the job run much faster.

After the job is complete, you can see the result in s3://xxxx-common-crawl/output/, in Parquet format.

Implement customized possessing logic

The Common Crawl GitHub repo provides a common approach to process WARC files. Generally, you can extend the CCSparkJob to override a single method (process_record), which is sufficient for many cases.

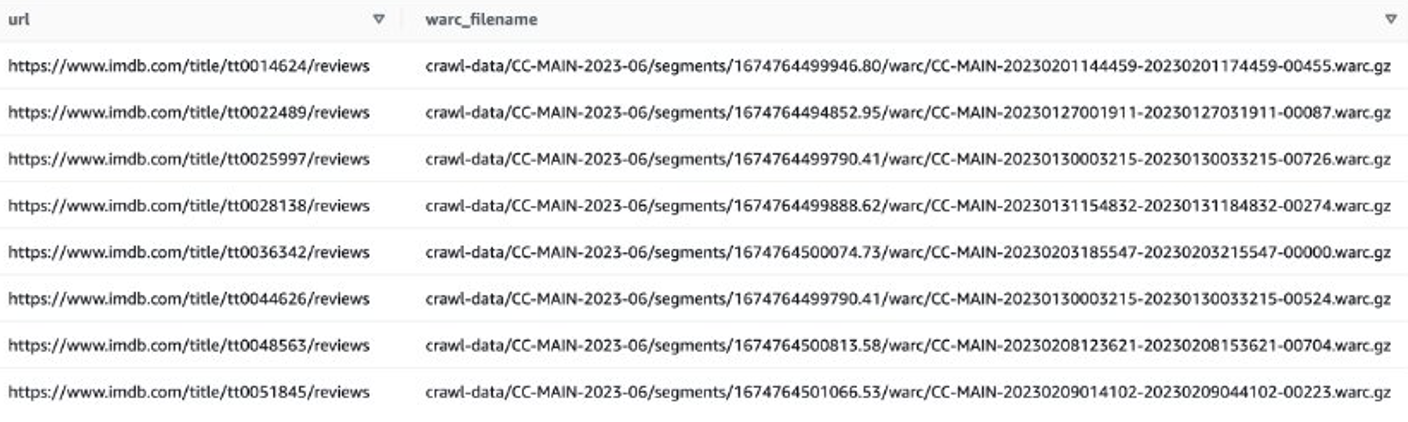
Let’s look at an example to get the IMDB reviews of recent movies. First, you need to filter out files on the IMDB site:

SELECT
  url,
  warc_filename,
  url_host_name
FROM  ccindex
WHERE  (crawl = 'CC-MAIN-2023-06'
  OR crawl = 'CC-MAIN-2023-40')
  AND subset = 'warc'
  AND url like  'https://www.imdb.com/title/%/reviews'
LIMIT  1000

Then you can get WARC file lists that contain IMDB review data, and save the WARC file names as a list in a text file.

Alternatively, you can use EMR Spark get the WARC file list and store it in Amazon S3. For example:

sql  = """SELECT
  warc_filename
FROM  ccindex
WHERE  (crawl = 'CC-MAIN-2023-06'
  OR crawl = 'CC-MAIN-2023-40')
  AND subset = 'warc'
  AND url like  'https://www.imdb.com/title/%/reviews'
"""

warc_list  = spark.sql(sql)

#  write result list to s3
warc_list.coalesce(1).write.mode("overwrite").text("s3://xxxx-common-crawl/warclist/imdb_warclist")

The output file should look similar to s3://xxxx-common-crawl/warclist/imdb_warclist/part-00000-6af12797-0cdc-4ef2-a438-cf2b935f2ffd-c000.txt.

The next step is to extract user reviews from these WARC files. You can extend the CCSparkJob to override the process_record() method:

from  sparkcc import CCSparkJob
from  bs4 import BeautifulSoup
from  urllib.parse import urlsplit
 
class  IMDB_Extract_Job(CCSparkJob):
    name = "IMDB_Reviews"
 
    def process_record(self, record):
        if self.is_response_record(record):
            # WARC response record
            domain =  urlsplit(record.rec_headers['WARC-Target-URI']).hostname
            if domain == 'www.imdb.com':
                # get web contents
                contents = (
                    record.content_stream()
                        .read()
                        .decode("utf-8", "replace")
                )
 
                # parse with beautiful soup
                soup =  BeautifulSoup(contents, "html.parser")
 
                # get reviews
                review_divs =  soup.find_all(class_="text show-more__control")
                for div in review_divs:
                    yield div.text,1
 
 
if  __name__ == "__main__":
    job = IMDB_Extract_Job()
    job.run()

You can save the preceding script as imdb_extractor.py, which you’ll use in the following steps. After you have prepared the data and scripts, you can use EMR Serverless to process the filtered data.

EMR Serverless

EMR Serverless is a serverless deployment option to run big data analytics applications using open source frameworks like Apache Spark and Hive without configuring, managing, and scaling clusters or servers.

With EMR Serverless, you can run analytics workloads at any scale with automatic scaling that resizes resources in seconds to meet changing data volumes and processing requirements. EMR Serverless automatically scales resources up and down to provide the right amount of capacity for your application, and you only pay for what you use.

Processing the Common Crawl dataset is generally a one-time processing task, making it suitable for EMR Serverless workloads.

Create an EMR Serverless application

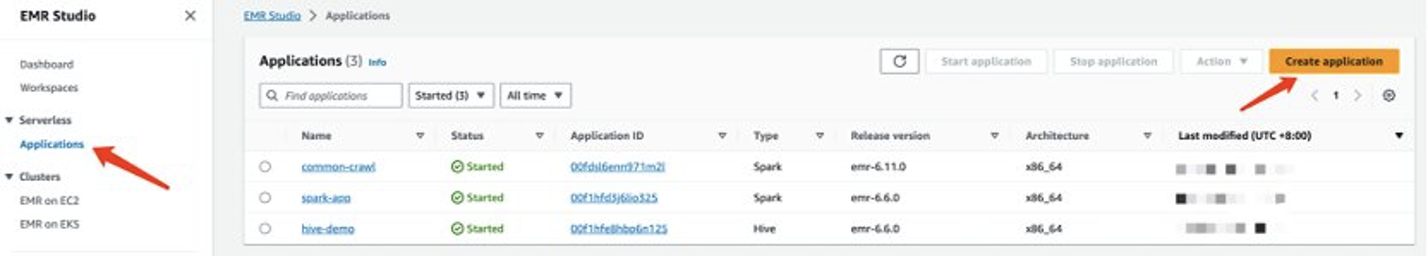
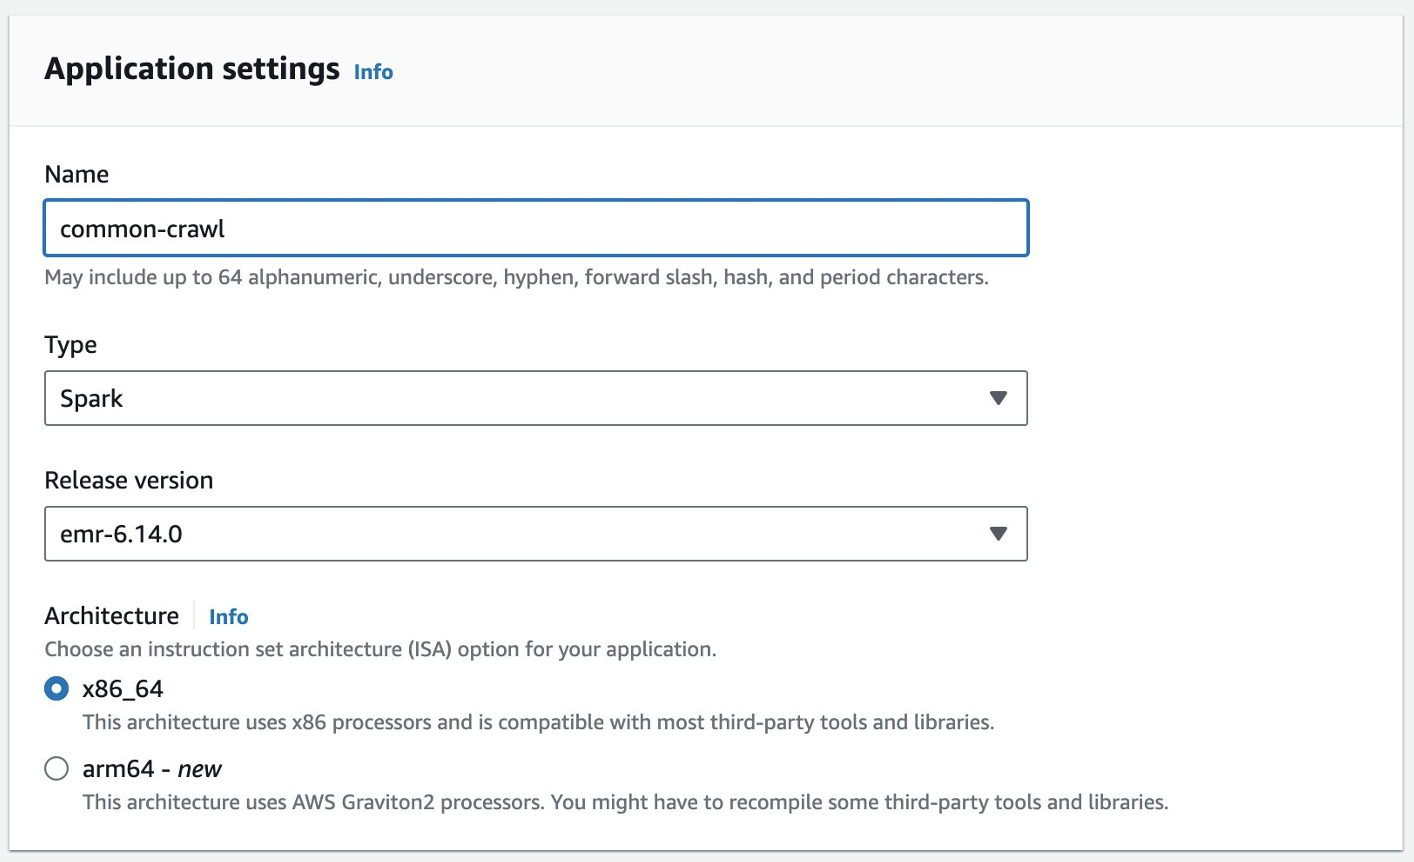
You can create an EMR Serverless application on the EMR Studio console. Complete the following steps:

  1. On the EMR Studio console, choose Applications under Serverless in the navigation pane.
  2. Choose Create application.

  1. Provide a name for the application and choose an Amazon EMR version.

  1. If access to VPC resources is required, add a customized network setting.

  1. Choose Create application.

Your Spark serverless environment will then be ready.

Before you can submit a job to EMR Spark Serverless, you still need to create an execution role. Refer to Getting started with Amazon EMR Serverless for more details.

Process Common Crawl data with EMR Serverless

After your EMR Spark Serverless application is ready, complete the following steps to process the data:

  1. Prepare a Conda environment and upload it to Amazon S3, which will be used as the environment in EMR Spark Serverless.
  2. Upload the scripts to be run to an S3 bucket. In the following example, there are two scripts:
    1. imbd_extractor.py – Customized logic to extract contents from the dataset. The contents can be found earlier in this post.
    2. cc-pyspark/sparkcc.py – The example PySpark framework from the Common Crawl GitHub repo, which is necessary to be included.
  3. Submit the PySpark job to EMR Serverless Spark. Define the following parameters to run this example in your environment:
    1. application-id – The application ID of your EMR Serverless application.
    2. execution-role-arn – Your EMR Serverless execution role. To create it, refer to Create a job runtime role.
    3. WARC file location – The location of your WARC files. s3://xxxx-common-crawl/warclist/imdb_warclist/part-00000-6af12797-0cdc-4ef2-a438-cf2b935f2ffd-c000.txt contains the filtered WARC file list, which you obtained earlier in this post.
    4. spark.sql.warehouse.dir – The default warehouse location (use your S3 directory).
    5. spark.archives – The S3 location of the prepared Conda environment.
    6. spark.submit.pyFiles – The prepared PySpark script sparkcc.py.

See the following code:

# 1. create conda environment
conda  create -y -n imdb -c dmnapolitano python=3.7 botocore boto3 ujson requests  conda-pack warcio bs4
 
# 2. package the conda  env, and upload to s3
conda  activate imdb 
conda  pack -o imdbenv.tar.gz
aws  s3 cp imdbenv.tar.gz s3://xxxx-common-crawl/env/
 
# 3. upload scripts to S3
aws  s3 cp imdb_extractor.py s3://xxxx-common-crawl/scripts/
aws  s3 cp cc-pyspark/sparkcc.py s3://xxxx-common-crawl/scripts/
 
# 4. submit job to EMR Serverless
#!/bin/bash
aws  emr-serverless start-job-run \
    --application-id 00fdsobht2skro2l \
    --execution-role-arn  arn:aws:iam::xxxx:role/EMR-Serverless-JobExecutionRole \
    --name imdb-retrive \
    --job-driver '{
        "sparkSubmit": {
          "entryPoint":  "s3://xxxx-common-crawl/scripts/imdb_extractor.py",
          "entryPointArguments":  ["--input_base_url" ,"s3://commoncrawl/",  "s3://xxxx-common-crawl/warclist/imdb_warclist/part-00000-6af12797-0cdc-4ef2-a438-cf2b935f2ffd-c000.txt",  "imdb_reviews", "--num_output_partitions",  "1"],
          "sparkSubmitParameters":  "--conf spark.sql.warehouse.dir=s3://xxxx-common-crawl/output/ --conf  spark.network.timeout=10000000 —conf  spark.executor.heartbeatInterval=10000000 —conf spark.executor.instances=100  —conf spark.executor.cores=4 —conf spark.executor.memory=16g —conf  spark.driver.memory=16g   —conf  spark.archives=s3://xxxx-common-crawl/env/imdbenv.tar.gz#environment —conf  spark.emr-serverless.driverEnv.PYSPARK_DRIVER_PYTHON=./environment/bin/python  —conf spark.emr-serverless.driverEnv.PYSPARK_PYTHON=./environment/bin/python  —conf spark.executorEnv.PYSPARK_PYTHON=./environment/bin/python —conf  spark.submit.pyFiles=s3://xxxx-common-crawl/scripts/sparkcc.py“
        }
}'

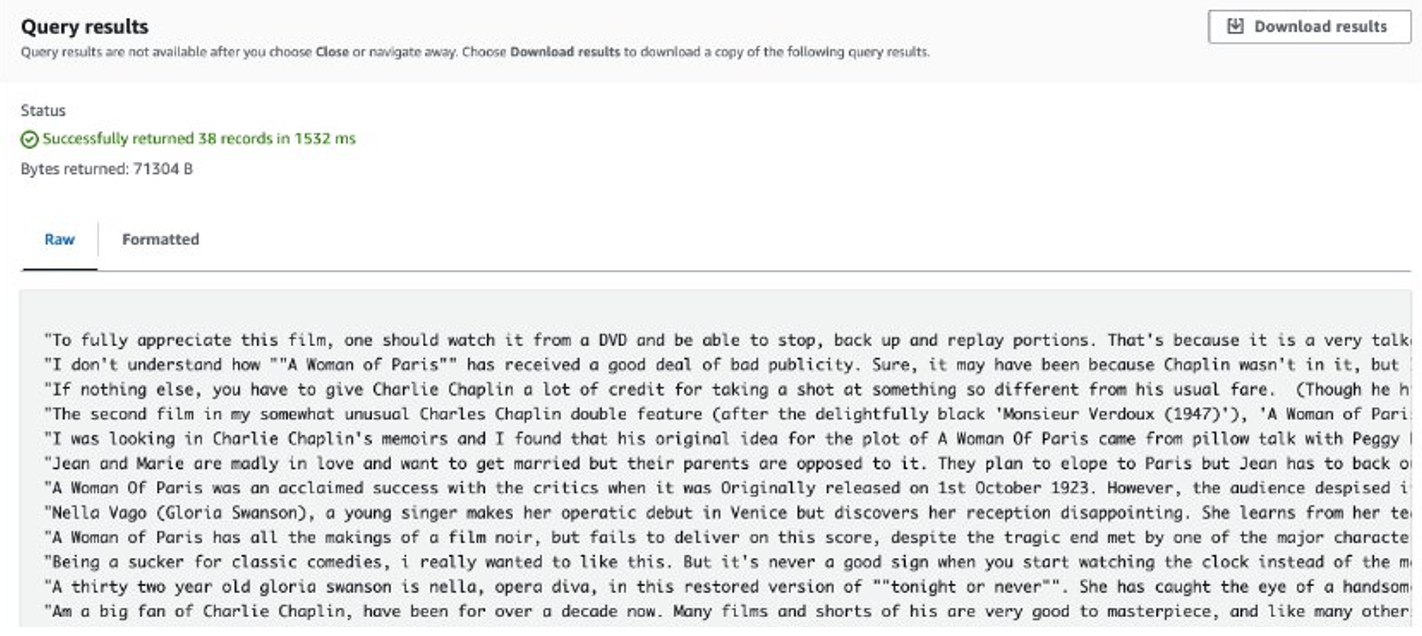
After the job is complete, the extracted reviews are stored in Amazon S3. To check the contents, you can use Amazon S3 Select, as shown in the following screenshot.

Considerations

The following are the points to consider when dealing with massive amounts of data with customized code:

  • Some third-party Python libraries may not be available in Conda. In such cases, you can switch to a Python virtual environment to build the PySpark runtime environment.
  • If there is a massive amount of data to be processed, try to create and use multiple EMR Serverless Spark applications to parallelize it. Each application deals with a subset of file lists.
  • You may encounter a slowdown issue with Amazon S3 when filtering or processing the Common Crawl data. This is because the S3 bucket storing the data is publicly accessible, and other users may access the data at the same time. To mitigate this issue, you can add a retry mechanism or sync specific data from the Common Crawl S3 bucket to your own bucket.

Fine-tune Llama 2 with SageMaker

After the data is prepared, you can fine-tune a Llama 2 model with it. You can do so using SageMaker JumpStart, without writing any code. For more information, refer to Fine-tune Llama 2 for text generation on Amazon SageMaker JumpStart.

In this scenario, you carry out a domain adaption fine-tuning. With this dataset, input consists of a CSV, JSON, or TXT file. You need to put all review data in a TXT file. To do so, you can submit a straightforward Spark job to EMR Spark Serverless. See the following sample code snippet:

# disable generating _SUCCESS file
spark.conf.set("mapreduce.fileoutputcommitter.marksuccessfuljobs",  "false")

data  = spark.read.parquet("s3://xxxx-common-crawl/output/imdb_reviews/")

data.select('Key').coalesce(1).write.mode("overwrite").text("s3://xxxx-common-crawl/llama2/train/")

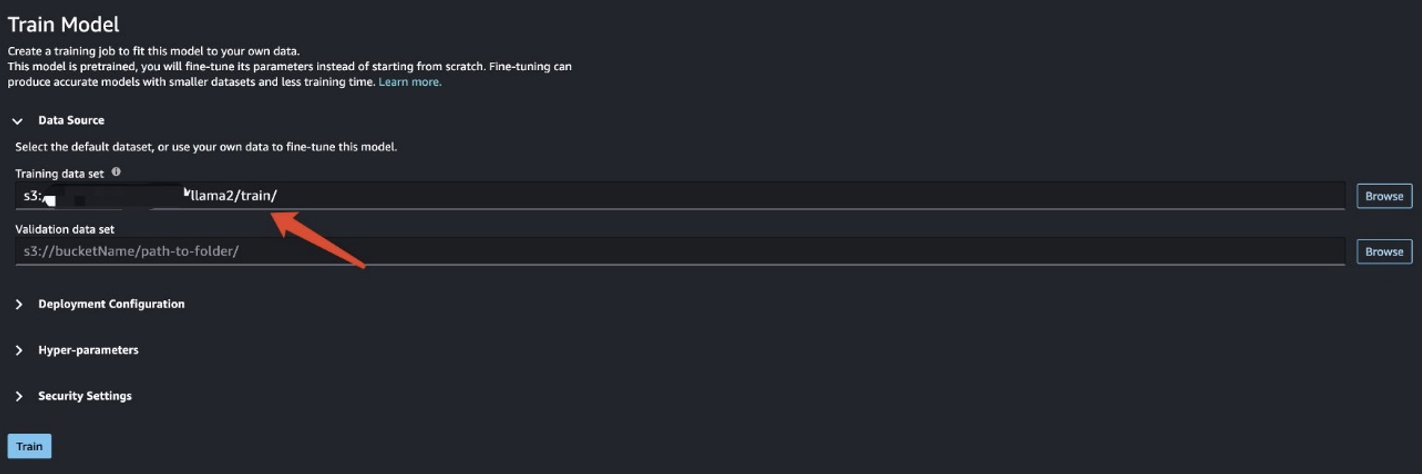
After you prepare the training data, enter the data location for Training data set, then choose Train.

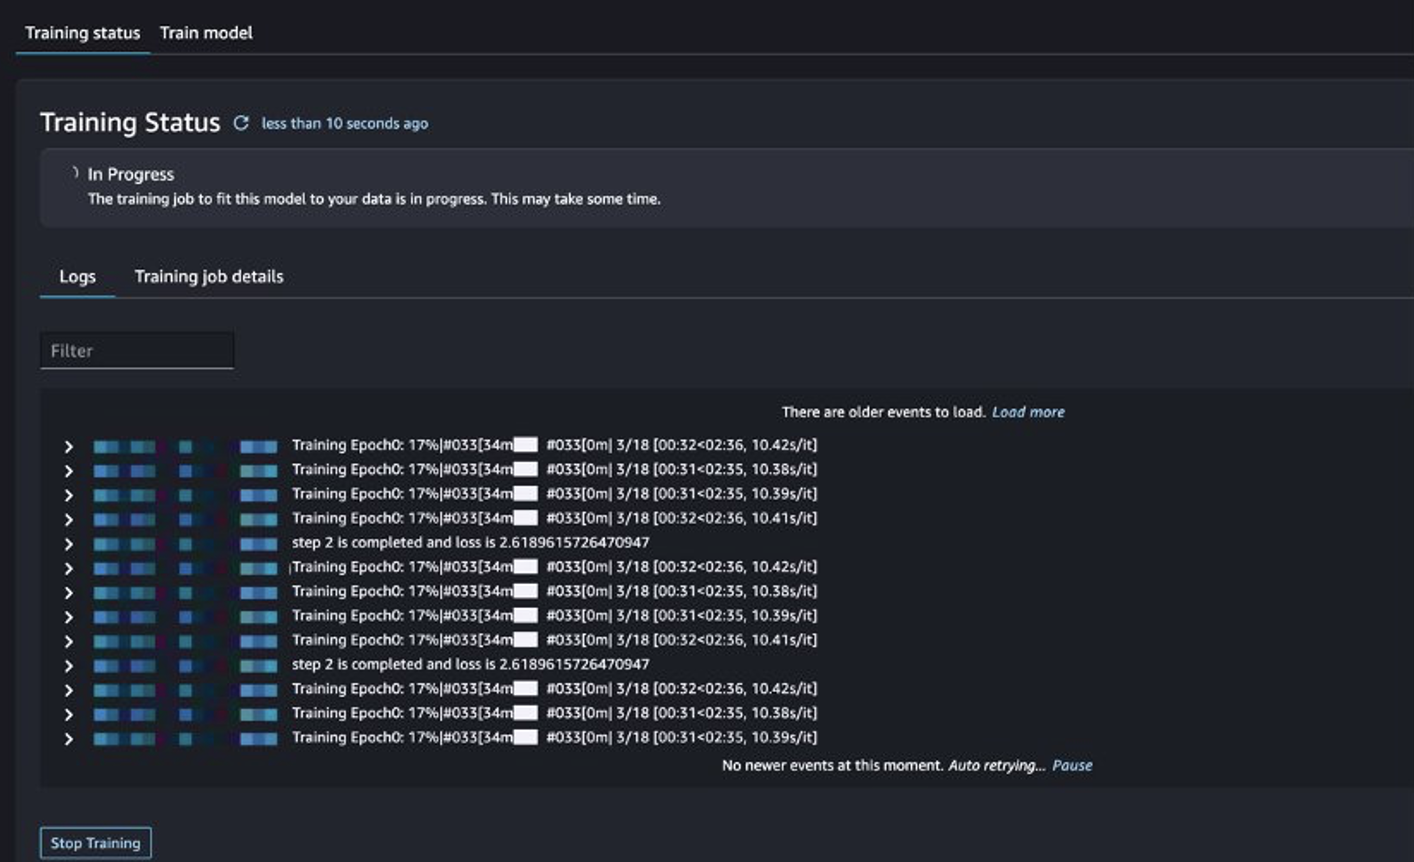
You can track the training job status.

Evaluate the fine-tuned model

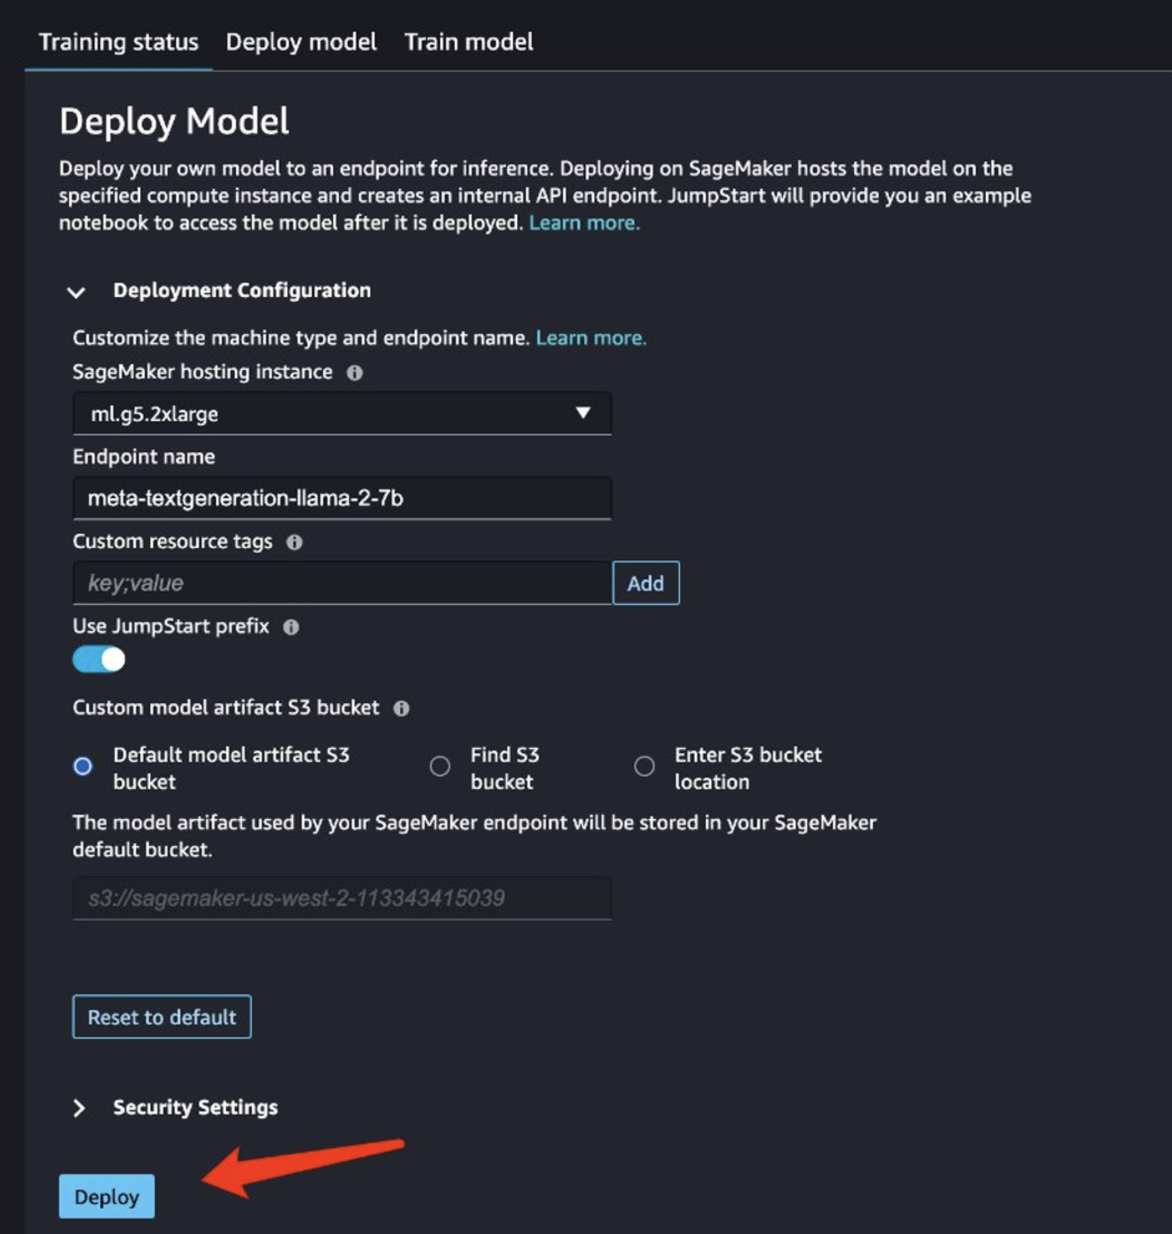
After training is complete, choose Deploy in SageMaker JumpStart to deploy your fine-tuned model.

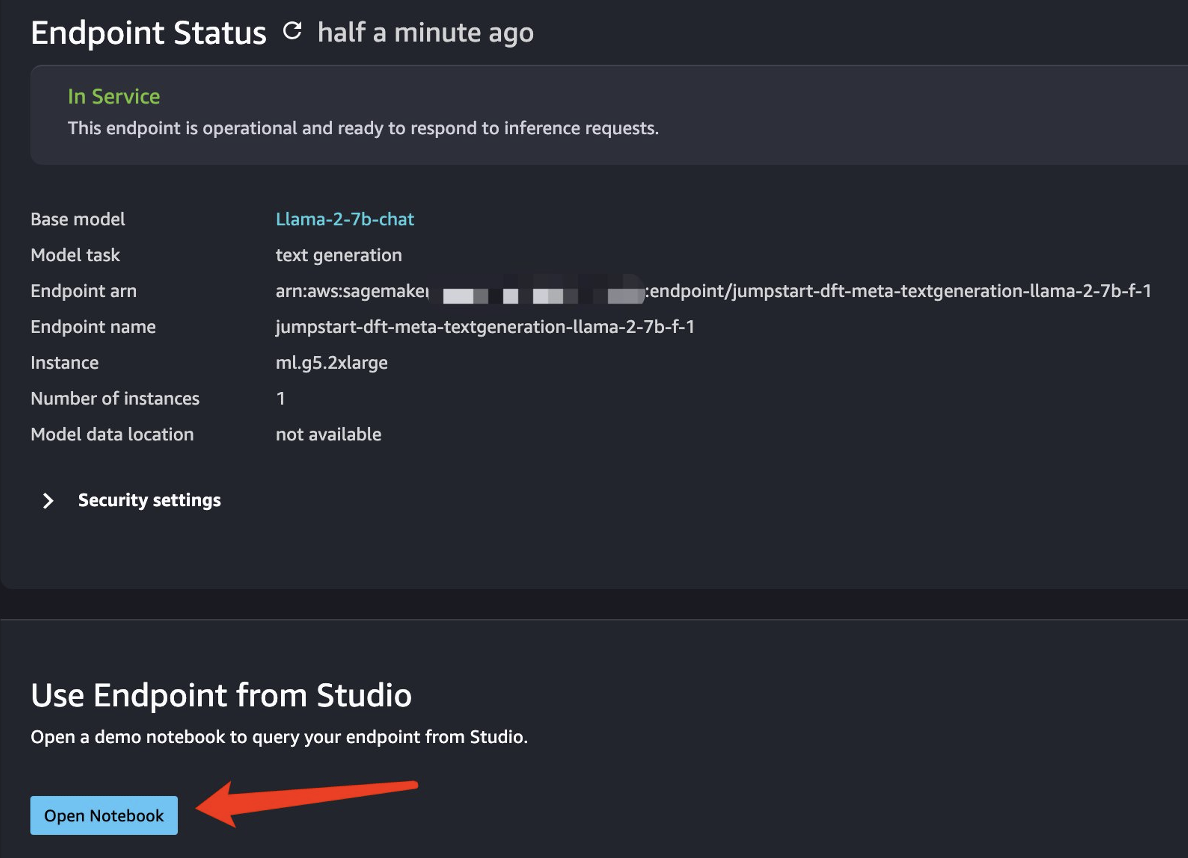
After the model is successfully deployed, choose Open Notebook, which redirects you to a prepared Jupyter notebook where you can run your Python code.

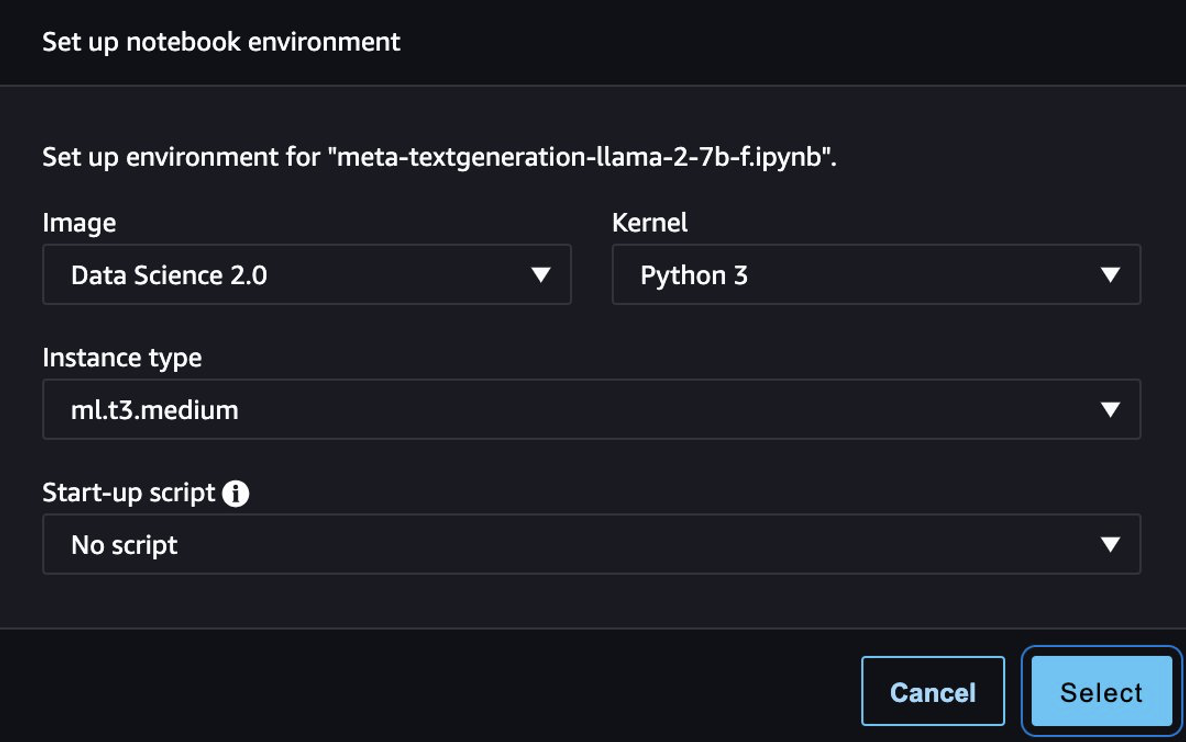
You can use the image Data Science 2.0 and the Python 3 kernel for the notebook.

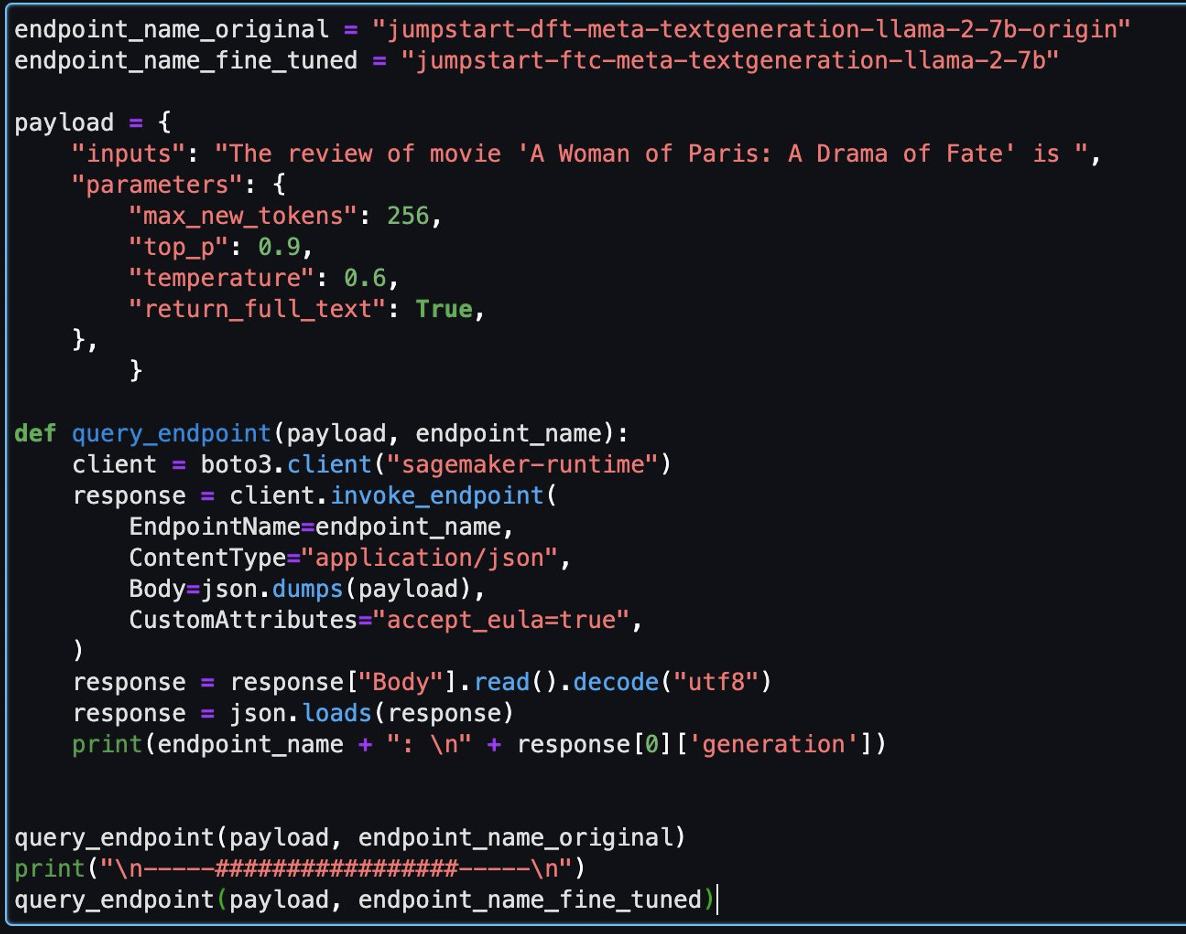
Then, you can evaluate the fine-tuned model and the original model in this notebook.

endpoint_name_original = "jumpstart-dft-meta-textgeneration-llama-2-7b-origin"
endpoint_name_fine_tuned = "jumpstart-ftc-meta-textgeneration-llama-2-7b"

payload = {
    "inputs": "The review of movie 'A Woman of Paris: A Drama of Fate' is ",
    "parameters": {
        "max_new_tokens": 256,
        "top_p": 0.9,
        "temperature": 0.6,
        "return_full_text": True,
    },
        }
    
def query_endpoint(payload, endpoint_name):
    client = boto3.client("sagemaker-runtime")
    response = client.invoke_endpoint(
        EndpointName=endpoint_name,
        ContentType="application/json",
        Body=json.dumps(payload),
        CustomAttributes="accept_eula=true",
    )
    response = response["Body"].read().decode("utf8")
    response = json.loads(response)
    print(endpoint_name + ": \n" + response[0]['generation'])


query_endpoint(payload, endpoint_name_original)
print("\n-----#################-----\n")
query_endpoint(payload, endpoint_name_fine_tuned)

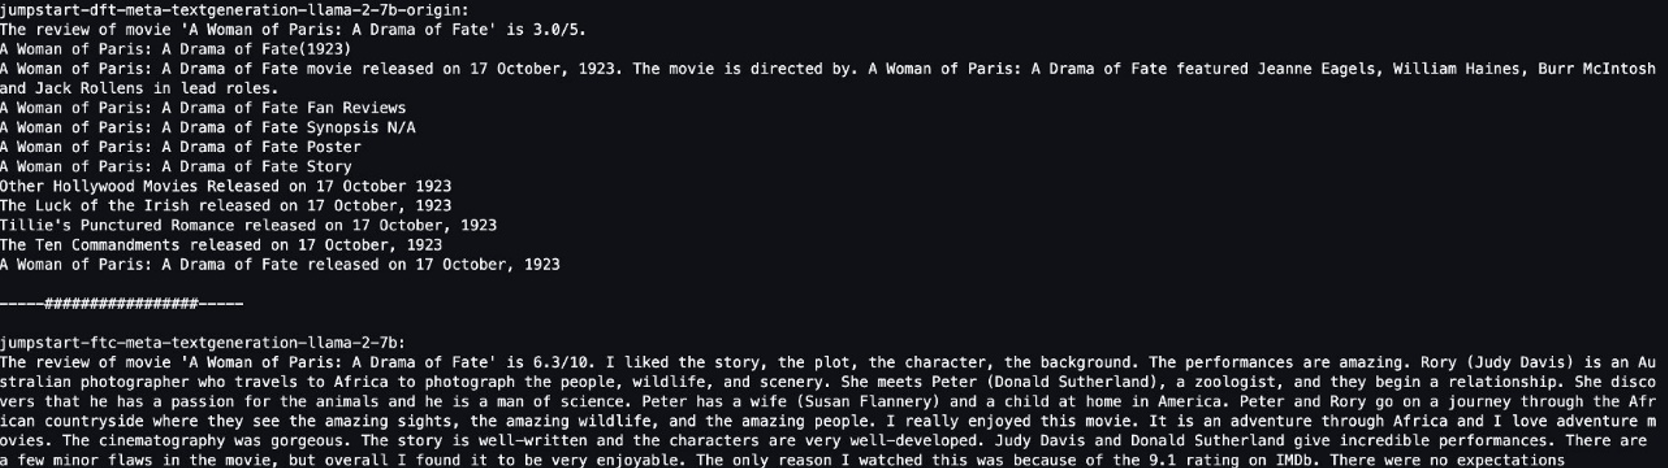
The following are two responses returned by the original model and fine-tuned model for the same question.

We provided both models with the same sentence: “The review of movie ‘A Woman of Paris: A Drama of Fate’ is” and let them complete the sentence.

The original model outputs meaningless sentences:

"The review of movie 'A woman of Paris: A Drama of Fate' is 3.0/5.

A Woman of Paris: A Drama of Fate(1923)

A Woman of Paris: A Drama of Fate movie released on 17 October, 1992. The movie is directed by. A Woman of Paris: A Drama of Fate featured Jeanne Eagles, William Haines, Burr McIntosh and Jack Rollens in lead rols.

..."

In contrast, the fine-tuned model’s outputs are more like a movie review:

" The review of movie 'A Woman of Paris: A Drama of Fate' is 6.3/10. I liked the story, the plot, the character, the background. The performances are amazing. Rory (Judy Davis) is an Australian photographer who travels to Africa to photograph the people, wildlife, and scenery. She meets Peter (Donald Sutherland), a zoologist, and they begin a relationship..."

Obviously, the fine-tuned model performs better in this specific scenario.

Clean up

After you finish this exercise, complete the following steps to clean up your resources:

  1. Delete the S3 bucket that stores the cleaned dataset.
  2. Stop the EMR Serverless environment.
  3. Delete the SageMaker endpoint that hosts the LLM model.
  4. Delete the SageMaker domain that runs your notebooks.

The application you created should stop automatically after 15 minutes of inactivity by default.

Generally, you don’t need to clean up the Athena environment because there are no charges when you’re not using it.

Conclusion

In this post, we introduced the Common Crawl dataset and how to use EMR Serverless to process the data for LLM fine-tuning. Then we demonstrated how to use SageMaker JumpStart to fine-tune the LLM and deploy it without any code. For more use cases of EMR Serverless, refer to Amazon EMR Serverless. For more information about hosting and fine-tuning models on Amazon SageMaker JumpStart, refer to the Sagemaker JumpStart documentation.


About the Authors

Shijian Tang is a Analytics Specialist Solution Architect at Amazon Web Services.

Matthew Liem is a Senior Solution Architecture Manager at Amazon Web Services.

Dalei Xu is a Analytics Specialist Solution Architect at Amazon Web Services.

Yuanjun Xiao is a Senior Solution Architect at Amazon Web Services.

Mastering market dynamics: Transforming transaction cost analytics with ultra-precise Tick History – PCAP and Amazon Athena for Apache Spark

Post Syndicated from Pramod Nayak original https://aws.amazon.com/blogs/big-data/mastering-market-dynamics-transforming-transaction-cost-analytics-with-ultra-precise-tick-history-pcap-and-amazon-athena-for-apache-spark/

This post is cowritten with Pramod Nayak, LakshmiKanth Mannem and Vivek Aggarwal from the Low Latency Group of LSEG.

Transaction cost analysis (TCA) is widely used by traders, portfolio managers, and brokers for pre-trade and post-trade analysis, and helps them measure and optimize transaction costs and the effectiveness of their trading strategies. In this post, we analyze options bid-ask spreads from the LSEG Tick History – PCAP dataset using Amazon Athena for Apache Spark. We show you how to access data, define custom functions to apply on data, query and filter the dataset, and visualize the results of the analysis, all without having to worry about setting up infrastructure or configuring Spark, even for large datasets.

Background

Options Price Reporting Authority (OPRA) serves as a crucial securities information processor, collecting, consolidating, and disseminating last sale reports, quotes, and pertinent information for US Options. With 18 active US Options exchanges and over 1.5 million eligible contracts, OPRA plays a pivotal role in providing comprehensive market data.

On February 5, 2024, the Securities Industry Automation Corporation (SIAC) is set to upgrade the OPRA feed from 48 to 96 multicast channels. This enhancement aims to optimize symbol distribution and line capacity utilization in response to escalating trading activity and volatility in the US options market. SIAC has recommended that firms prepare for peak data rates of up to 37.3 GBits per second.

Despite the upgrade not immediately altering the total volume of published data, it enables OPRA to disseminate data at a significantly faster rate. This transition is crucial for addressing the demands of the dynamic options market.

OPRA stands out as one the most voluminous feeds, with a peak of 150.4 billion messages in a single day in Q3 2023 and a capacity headroom requirement of 400 billion messages over a single day. Capturing every single message is critical for transaction cost analytics, market liquidity monitoring, trading strategy evaluation, and market research.

About the data

LSEG Tick History – PCAP is a cloud-based repository, exceeding 30 PB, housing ultra-high-quality global market data. This data is meticulously captured directly within the exchange data centers, employing redundant capture processes strategically positioned in major primary and backup exchange data centers worldwide. LSEG’s capture technology ensures lossless data capture and uses a GPS time-source for nanosecond timestamp precision. Additionally, sophisticated data arbitrage techniques are employed to seamlessly fill any data gaps. Subsequent to capture, the data undergoes meticulous processing and arbitration, and is then normalized into Parquet format using LSEG’s Real Time Ultra Direct (RTUD) feed handlers.

The normalization process, which is integral to preparing the data for analysis, generates up to 6 TB of compressed Parquet files per day. The massive volume of data is attributed to the encompassing nature of OPRA, spanning multiple exchanges, and featuring numerous options contracts characterized by diverse attributes. Increased market volatility and market making activity on the options exchanges further contribute to the volume of data published on OPRA.

The attributes of Tick History – PCAP enable firms to conduct various analyses, including the following:

  • Pre-trade analysis – Evaluate potential trade impact and explore different execution strategies based on historical data
  • Post-trade evaluation – Measure actual execution costs against benchmarks to assess the performance of execution strategies
  • Optimized execution – Fine-tune execution strategies based on historical market patterns to minimize market impact and reduce overall trading costs
  • Risk management – Identify slippage patterns, identify outliers, and proactively manage risks associated with trading activities
  • Performance attribution – Separate the impact of trading decisions from investment decisions when analyzing portfolio performance

The LSEG Tick History – PCAP dataset is available in AWS Data Exchange and can be accessed on AWS Marketplace. With AWS Data Exchange for Amazon S3, you can access PCAP data directly from LSEG’s Amazon Simple Storage Service (Amazon S3) buckets, eliminating the need for firms to store their own copy of the data. This approach streamlines data management and storage, providing clients immediate access to high-quality PCAP or normalized data with ease of use, integration, and substantial data storage savings.

Athena for Apache Spark

For analytical endeavors, Athena for Apache Spark offers a simplified notebook experience accessible through the Athena console or Athena APIs, allowing you to build interactive Apache Spark applications. With an optimized Spark runtime, Athena helps the analysis of petabytes of data by dynamically scaling the number of Spark engines is less than a second. Moreover, common Python libraries such as pandas and NumPy are seamlessly integrated, allowing for the creation of intricate application logic. The flexibility extends to the importation of custom libraries for use in notebooks. Athena for Spark accommodates most open-data formats and is seamlessly integrated with the AWS Glue Data Catalog.

Dataset

For this analysis, we used the LSEG Tick History – PCAP OPRA dataset from May 17, 2023. This dataset comprises the following components:

  • Best bid and offer (BBO) – Reports the highest bid and lowest ask for a security at a given exchange
  • National best bid and offer (NBBO) – Reports the highest bid and lowest ask for a security across all exchanges
  • Trades – Records completed trades across all exchanges

The dataset involves the following data volumes:

  • Trades – 160 MB distributed across approximately 60 compressed Parquet files
  • BBO – 2.4 TB distributed across approximately 300 compressed Parquet files
  • NBBO – 2.8 TB distributed across approximately 200 compressed Parquet files

Analysis overview

Analyzing OPRA Tick History data for Transaction Cost Analysis (TCA) involves scrutinizing market quotes and trades around a specific trade event. We use the following metrics as part of this study:

  • Quoted spread (QS) – Calculated as the difference between the BBO ask and the BBO bid
  • Effective spread (ES) – Calculated as the difference between the trade price and the midpoint of the BBO (BBO bid + (BBO ask – BBO bid)/2)
  • Effective/quoted spread (EQF) – Calculated as (ES / QS) * 100

We calculate these spreads before the trade and additionally at four intervals after the trade (just after, 1 second, 10 seconds, and 60 seconds after the trade).

Configure Athena for Apache Spark

To configure Athena for Apache Spark, complete the following steps:

  1. On the Athena console, under Get started, select Analyze your data using PySpark and Spark SQL.
  2. If this is your first time using Athena Spark, choose Create workgroup.
  3. For Workgroup name¸ enter a name for the workgroup, such as tca-analysis.
  4. In the Analytics engine section, select Apache Spark.
  5. In the Additional configurations section, you can choose Use defaults or provide a custom AWS Identity and Access Management (IAM) role and Amazon S3 location for calculation results.
  6. Choose Create workgroup.
  7. After you create the workgroup, navigate to the Notebooks tab and choose Create notebook.
  8. Enter a name for your notebook, such as tca-analysis-with-tick-history.
  9. Choose Create to create your notebook.

Launch your notebook

If you have already created a Spark workgroup, select Launch notebook editor under Get started.


After your notebook is created, you will be redirected to the interactive notebook editor.


Now we can add and run the following code to our notebook.

Create an analysis

Complete the following steps to create an analysis:

  • Import common libraries:
import pandas as pd
import plotly.express as px
import plotly.graph_objects as go
  • Create our data frames for BBO, NBBO, and trades:
bbo_quote = spark.read.parquet(f"s3://<bucket>/mt=bbo_quote/f=opra/dt=2023-05-17/*")
bbo_quote.createOrReplaceTempView("bbo_quote")
nbbo_quote = spark.read.parquet(f"s3://<bucket>/mt=nbbo_quote/f=opra/dt=2023-05-17/*")
nbbo_quote.createOrReplaceTempView("nbbo_quote")
trades = spark.read.parquet(f"s3://<bucket>/mt=trade/f=opra/dt=2023-05-17/29_1.parquet")
trades.createOrReplaceTempView("trades")
  • Now we can identify a trade to use for transaction cost analysis:
filtered_trades = spark.sql("select Product, Price,Quantity, ReceiptTimestamp, MarketParticipant from trades")

We get the following output:

+---------------------+---------------------+---------------------+-------------------+-----------------+ 
|Product |Price |Quantity |ReceiptTimestamp |MarketParticipant| 
+---------------------+---------------------+---------------------+-------------------+-----------------+ 
|QQQ 230518C00329000|1.1700000000000000000|10.0000000000000000000|1684338565538021907,NYSEArca|
|QQQ 230518C00329000|1.1700000000000000000|20.0000000000000000000|1684338576071397557,NASDAQOMXPHLX|
|QQQ 230518C00329000|1.1600000000000000000|1.0000000000000000000|1684338579104713924,ISE|
|QQQ 230518C00329000|1.1400000000000000000|1.0000000000000000000|1684338580263307057,NASDAQOMXBX_Options|
|QQQ 230518C00329000|1.1200000000000000000|1.0000000000000000000|1684338581025332599,ISE|
+---------------------+---------------------+---------------------+-------------------+-----------------+

We use the highlighted trade information going forward for the trade product (tp), trade price (tpr), and trade time (tt).

  • Here we create a number of helper functions for our analysis
def calculate_es_qs_eqf(df, trade_price):
    df['BidPrice'] = df['BidPrice'].astype('double')
    df['AskPrice'] = df['AskPrice'].astype('double')
    df["ES"] = ((df["AskPrice"]-df["BidPrice"])/2) - trade_price
    df["QS"] = df["AskPrice"]-df["BidPrice"]
    df["EQF"] = (df["ES"]/df["QS"])*100
    return df

def get_trade_before_n_seconds(trade_time, df, seconds=0, groupby_col = None):
    nseconds=seconds*1000000000
    nseconds += trade_time
    ret_df = df[df['ReceiptTimestamp'] < nseconds].groupby(groupby_col).last()
    ret_df['BidPrice'] = ret_df['BidPrice'].astype('double')
    ret_df['AskPrice'] = ret_df['AskPrice'].astype('double')
    ret_df = ret_df.reset_index()
    return ret_df

def get_trade_after_n_seconds(trade_time, df, seconds=0, groupby_col = None):
    nseconds=seconds*1000000000
    nseconds += trade_time
    ret_df = df[df['ReceiptTimestamp'] > nseconds].groupby(groupby_col).first()
    ret_df['BidPrice'] = ret_df['BidPrice'].astype('double')
    ret_df['AskPrice'] = ret_df['AskPrice'].astype('double')
    ret_df = ret_df.reset_index()
    return ret_df

def get_nbbo_trade_before_n_seconds(trade_time, df, seconds=0):
    nseconds=seconds*1000000000
    nseconds += trade_time
    ret_df = df[df['ReceiptTimestamp'] < nseconds].iloc[-1:]
    ret_df['BidPrice'] = ret_df['BidPrice'].astype('double')
    ret_df['AskPrice'] = ret_df['AskPrice'].astype('double')
    return ret_df

def get_nbbo_trade_after_n_seconds(trade_time, df, seconds=0):
    nseconds=seconds*1000000000
    nseconds += trade_time
    ret_df = df[df['ReceiptTimestamp'] > nseconds].iloc[:1]
    ret_df['BidPrice'] = ret_df['BidPrice'].astype('double')
    ret_df['AskPrice'] = ret_df['AskPrice'].astype('double')
    return ret_df
  • In the following function, we create the dataset that contains all the quotes before and after the trade. Athena Spark automatically determines how many DPUs to launch for processing our dataset.
def get_tca_analysis_via_df_single_query(trade_product, trade_price, trade_time):
    # BBO quotes
    bbos = spark.sql(f"SELECT Product, ReceiptTimestamp, AskPrice, BidPrice, MarketParticipant FROM bbo_quote where Product = '{trade_product}';")
    bbos = bbos.toPandas()

    bbo_just_before = get_trade_before_n_seconds(trade_time, bbos, seconds=0, groupby_col='MarketParticipant')
    bbo_just_after = get_trade_after_n_seconds(trade_time, bbos, seconds=0, groupby_col='MarketParticipant')
    bbo_1s_after = get_trade_after_n_seconds(trade_time, bbos, seconds=1, groupby_col='MarketParticipant')
    bbo_10s_after = get_trade_after_n_seconds(trade_time, bbos, seconds=10, groupby_col='MarketParticipant')
    bbo_60s_after = get_trade_after_n_seconds(trade_time, bbos, seconds=60, groupby_col='MarketParticipant')
    
    all_bbos = pd.concat([bbo_just_before, bbo_just_after, bbo_1s_after, bbo_10s_after, bbo_60s_after], ignore_index=True, sort=False)
    bbos_calculated = calculate_es_qs_eqf(all_bbos, trade_price)

    #NBBO quotes
    nbbos = spark.sql(f"SELECT Product, ReceiptTimestamp, AskPrice, BidPrice, BestBidParticipant, BestAskParticipant FROM nbbo_quote where Product = '{trade_product}';")
    nbbos = nbbos.toPandas()

    nbbo_just_before = get_nbbo_trade_before_n_seconds(trade_time,nbbos, seconds=0)
    nbbo_just_after = get_nbbo_trade_after_n_seconds(trade_time, nbbos, seconds=0)
    nbbo_1s_after = get_nbbo_trade_after_n_seconds(trade_time, nbbos, seconds=1)
    nbbo_10s_after = get_nbbo_trade_after_n_seconds(trade_time, nbbos, seconds=10)
    nbbo_60s_after = get_nbbo_trade_after_n_seconds(trade_time, nbbos, seconds=60)

    all_nbbos = pd.concat([nbbo_just_before, nbbo_just_after, nbbo_1s_after, nbbo_10s_after, nbbo_60s_after], ignore_index=True, sort=False)
    nbbos_calculated = calculate_es_qs_eqf(all_nbbos, trade_price)

    calc = pd.concat([bbos_calculated, nbbos_calculated], ignore_index=True, sort=False)
    
    return calc
  • Now let’s call the TCA analysis function with the information from our selected trade:
tp = "QQQ 230518C00329000"
tpr = 1.16
tt = 1684338579104713924
c = get_tca_analysis_via_df_single_query(tp, tpr, tt)

Visualize the analysis results

Now let’s create the data frames we use for our visualization. Each data frame contains quotes for one of the five time intervals for each data feed (BBO, NBBO):

bbo = c[c['MarketParticipant'].isin(['BBO'])]
bbo_bef = bbo[bbo['ReceiptTimestamp'] < tt]
bbo_aft_0 = bbo[bbo['ReceiptTimestamp'].between(tt,tt+1000000000)]
bbo_aft_1 = bbo[bbo['ReceiptTimestamp'].between(tt+1000000000,tt+10000000000)]
bbo_aft_10 = bbo[bbo['ReceiptTimestamp'].between(tt+10000000000,tt+60000000000)]
bbo_aft_60 = bbo[bbo['ReceiptTimestamp'] > (tt+60000000000)]

nbbo = c[~c['MarketParticipant'].isin(['BBO'])]
nbbo_bef = nbbo[nbbo['ReceiptTimestamp'] < tt]
nbbo_aft_0 = nbbo[nbbo['ReceiptTimestamp'].between(tt,tt+1000000000)]
nbbo_aft_1 = nbbo[nbbo['ReceiptTimestamp'].between(tt+1000000000,tt+10000000000)]
nbbo_aft_10 = nbbo[nbbo['ReceiptTimestamp'].between(tt+10000000000,tt+60000000000)]
nbbo_aft_60 = nbbo[nbbo['ReceiptTimestamp'] > (tt+60000000000)]

In the following sections, we provide example code to create different visualizations.

Plot QS and NBBO before the trade

Use the following code to plot the quoted spread and NBBO before the trade:

fig = px.bar(title="Quoted Spread Before The Trade",
    x=bbo_bef.MarketParticipant,
    y=bbo_bef['QS'],
    labels={'x': 'Market', 'y':'Quoted Spread'})
fig.add_hline(y=nbbo_bef.iloc[0]['QS'],
    line_width=1, line_dash="dash", line_color="red",
    annotation_text="NBBO", annotation_font_color="red")
%plotly fig

Plot QS for each market and NBBO after the trade

Use the following code to plot the quoted spread for each market and NBBO immediately after the trade:

fig = px.bar(title="Quoted Spread After The Trade",
    x=bbo_aft_0.MarketParticipant,
    y=bbo_aft_0['QS'],
    labels={'x': 'Market', 'y':'Quoted Spread'})
fig.add_hline(
    y=nbbo_aft_0.iloc[0]['QS'],
    line_width=1, line_dash="dash", line_color="red",
    annotation_text="NBBO", annotation_font_color="red")
%plotly fig

Plot QS for each time interval and each market for BBO

Use the following code to plot the quoted spread for each time interval and each market for BBO:

fig = go.Figure(data=[
    go.Bar(name="before trade", x=bbo_bef.MarketParticipant.unique(), y=bbo_bef['QS']),
    go.Bar(name="0s after trade", x=bbo_aft_0.MarketParticipant.unique(), y=bbo_aft_0['QS']),
    go.Bar(name="1s after trade", x=bbo_aft_1.MarketParticipant.unique(), y=bbo_aft_1['QS']),
    go.Bar(name="10s after trade", x=bbo_aft_10.MarketParticipant.unique(), y=bbo_aft_10['QS']),
    go.Bar(name="60s after trade", x=bbo_aft_60.MarketParticipant.unique(), y=bbo_aft_60['QS'])])
fig.update_layout(barmode='group',title="BBO Quoted Spread Per Market/TimeFrame",
    xaxis={'title':'Market'},
    yaxis={'title':'Quoted Spread'})
%plotly fig

Plot ES for each time interval and market for BBO

Use the following code to plot the effective spread for each time interval and market for BBO:

fig = go.Figure(data=[
    go.Bar(name="before trade", x=bbo_bef.MarketParticipant.unique(), y=bbo_bef['ES']),
    go.Bar(name="0s after trade", x=bbo_aft_0.MarketParticipant.unique(), y=bbo_aft_0['ES']),
    go.Bar(name="1s after trade", x=bbo_aft_1.MarketParticipant.unique(), y=bbo_aft_1['ES']),
    go.Bar(name="10s after trade", x=bbo_aft_10.MarketParticipant.unique(), y=bbo_aft_10['ES']),
    go.Bar(name="60s after trade", x=bbo_aft_60.MarketParticipant.unique(), y=bbo_aft_60['ES'])])
fig.update_layout(barmode='group',title="BBO Effective Spread Per Market/TimeFrame",
    xaxis={'title':'Market'}, 
    yaxis={'title':'Effective Spread'})
%plotly fig

Plot EQF for each time interval and market for BBO

Use the following code to plot the effective/quoted spread for each time interval and market for BBO:

fig = go.Figure(data=[
    go.Bar(name="before trade", x=bbo_bef.MarketParticipant.unique(), y=bbo_bef['EQF']),
    go.Bar(name="0s after trade", x=bbo_aft_0.MarketParticipant.unique(), y=bbo_aft_0['EQF']),
    go.Bar(name="1s after trade", x=bbo_aft_1.MarketParticipant.unique(), y=bbo_aft_1['EQF']),
    go.Bar(name="10s after trade", x=bbo_aft_10.MarketParticipant.unique(), y=bbo_aft_10['EQF']),
    go.Bar(name="60s after trade", x=bbo_aft_60.MarketParticipant.unique(), y=bbo_aft_60['EQF'])])
fig.update_layout(barmode='group',title="BBO Effective/Quoted Spread Per Market/TimeFrame",
    xaxis={'title':'Market'}, 
    yaxis={'title':'Effective/Quoted Spread'})
%plotly fig

Athena Spark calculation performance

When you run a code block, Athena Spark automatically determines how many DPUs it requires to complete the calculation. In the last code block, where we call the tca_analysis function, we are actually instructing Spark to process the data, and we then convert the resulting Spark dataframes into Pandas dataframes. This constitutes the most intensive processing part of the analysis, and when Athena Spark runs this block, it shows the progress bar, elapsed time, and how many DPUs are processing data currently. For example, in the following calculation, Athena Spark is utilizing 18 DPUs.

When you configure your Athena Spark notebook, you have the option of setting the maximum number of DPUs that it can use. The default is 20 DPUs, but we tested this calculation with 10, 20, and 40 DPUs to demonstrate how Athena Spark automatically scales to run our analysis. We observed that Athena Spark scales linearly, taking 15 minutes and 21 seconds when the notebook was configured with a maximum of 10 DPUs, 8 minutes and 23 seconds when the notebook was configured with 20 DPUs, and 4 minutes and 44 seconds when the notebook was configured with 40 DPUs. Because Athena Spark charges based on DPU usage, at a per-second granularity, the cost of these calculations is similar, but if you set a higher maximum DPU value, Athena Spark can return the result of the analysis much faster. For more details on Athena Spark pricing please click here.

Conclusion

In this post, we demonstrated how you can use high-fidelity OPRA data from LSEG’s Tick History-PCAP to perform transaction cost analytics using Athena Spark. The availability of OPRA data in a timely manner, complemented with accessibility innovations of AWS Data Exchange for Amazon S3, strategically reduces the time to analytics for firms looking to create actionable insights for critical trading decisions. OPRA generates about 7 TB of normalized Parquet data each day, and managing the infrastructure to provide analytics based on OPRA data is challenging.

Athena’s scalability in handling large-scale data processing for Tick History – PCAP for OPRA data makes it a compelling choice for organizations seeking swift and scalable analytics solutions in AWS. This post shows the seamless interaction between the AWS ecosystem and Tick History-PCAP data and how financial institutions can take advantage of this synergy to drive data-driven decision-making for critical trading and investment strategies.


About the Authors

Pramod Nayak is the Director of Product Management of the Low Latency Group at LSEG. Pramod has over 10 years of experience in the financial technology industry, focusing on software development, analytics, and data management. Pramod is a former software engineer and passionate about market data and quantitative trading.

LakshmiKanth Mannem is a Product Manager in the Low Latency Group of LSEG. He focuses on data and platform products for the low-latency market data industry. LakshmiKanth helps customers build the most optimal solutions for their market data needs.

Vivek Aggarwal is a Senior Data Engineer in the Low Latency Group of LSEG. Vivek works on developing and maintaining data pipelines for processing and delivery of captured market data feeds and reference data feeds.

Alket Memushaj is a Principal Architect in the Financial Services Market Development team at AWS. Alket is responsible for technical strategy, working with partners and customers to deploy even the most demanding capital markets workloads to the AWS Cloud.

Data masking and granular access control using Amazon Macie and AWS Lake Formation

Post Syndicated from Iris Ferreira original https://aws.amazon.com/blogs/security/data-masking-and-granular-access-control-using-amazon-macie-and-aws-lake-formation/

Companies have been collecting user data to offer new products, recommend options more relevant to the user’s profile, or, in the case of financial institutions, to be able to facilitate access to higher credit lines or lower interest rates. However, personal data is sensitive as its use enables identification of the person using a specific system or application and in the wrong hands, this data might be used in unauthorized ways. Governments and organizations have created laws and regulations, such as General Data Protection Regulation (GDPR) in the EU, General Data Protection Law (LGPD) in Brazil, and technical guidance such as the Cloud Computing Implementation Guide published by the Association of Banks in Singapore (ABS), that specify what constitutes sensitive data and how companies should manage it. A common requirement is to ensure that consent is obtained for collection and use of personal data and that any data collected is anonymized to protect consumers from data breach risks.

In this blog post, we walk you through a proposed architecture that implements data anonymization by using granular access controls according to well-defined rules. It covers a scenario where a user might not have read access to data, but an application does. A common use case for this scenario is a data scientist working with sensitive data to train machine learning models. The training algorithm would have access to the data, but the data scientist would not. This approach helps reduce the risk of data leakage while enabling innovation using data.

Prerequisites

To implement the proposed solution, you must have an active AWS account and AWS Identity and Access Management (IAM) permissions to use the following services:

Note: If there’s a pre-existing Lake Formation configuration, there might be permission issues when testing this solution. We suggest that you test this solution on a development account that doesn’t yet have Lake Formation active. If you don’t have access to a development account, see more details about the permissions required on your role in the Lake Formation documentation.

You must give permission for AWS DMS to create the necessary resources, such as the EC2 instance where you will run DMS tasks. If you have ever worked with DMS, this permission should already exist. Otherwise, you can use CloudFormation to create the necessary roles to deploy the solution. To see if permission already exists, open the AWS Management Console and go to IAM, select Roles, and see if there is a role called dms-vpc-role. If not, you must create the role during deployment.

We use the Faker library to create dummy data consisting of the following tables:

  • Customer
  • Bank
  • Card

Solution overview

This architecture allows multiple data sources to send information to the data lake environment on AWS, where Amazon S3 is the central data store. After the data is stored in an S3 bucket, Macie analyzes the objects and identifies sensitive data using machine learning (ML) and pattern matching. AWS Glue then uses the information to run a workflow to anonymize the data.

Figure 1: Solution architecture for data ingestion and identification of PII

Figure 1: Solution architecture for data ingestion and identification of PII

We will describe two techniques used in the process: data masking and data encryption. After the workflow runs, the data is stored in a separate S3 bucket. This hierarchy of buckets is used to segregate access to data for different user personas.

Figure 1 depicts the solution architecture:

  1. The data source in the solution is an Amazon RDS database. Data can be stored in a database on an EC2 instance, in an on-premises server, or even deployed in a different cloud provider.
  2. AWS DMS uses full load, which allows data migration from the source (an Amazon RDS database) into the target S3 bucket — dcp-macie — as a one-time migration. New objects uploaded to the S3 bucket are automatically encrypted using server-side encryption (SSE-S3).
  3. A personally identifiable information (PII) detection pipeline is invoked after the new Amazon S3 objects are uploaded. Macie analyzes the objects and identifies values that are sensitive. Users can manually identify which fields and values within the files should be classified as sensitive or use the Macie automated sensitive data discovery capabilities.
  4. The sensitive values identified by Macie are sent to EventBridge, invoking Kinesis Data Firehose to store them in the dcp-glue S3 bucket. AWS Glue uses this data to know which fields to mask or encrypt using an encryption key stored in AWS KMS.
    1. Using EventBridge enables an event-based architecture. EventBridge is used as a bridge between Macie and Kinesis Data Firehose, integrating these services.
    2. Kinesis Data Firehose supports data buffering mitigating the risk of information loss when sent by Macie while reducing the overall cost of storing data in Amazon S3. It also allows data to be sent to other locations, such as Amazon Redshift or Splunk, making it available to be analyzed by other products.
  5. At the end of this step, Amazon S3 is invoked from a Lambda function that starts the AWS Glue workflow, which masks and encrypts the identified data.
    1. AWS Glue starts a crawler on the S3 bucket dcp-macie (a) and the bucket dcp-glue (b) to populate two tables, respectively, created as part of the AWS Glue service.
    2. After that, a Python script is run (c), querying the data in these tables. It uses this information to mask and encrypt the data and then store it in the prefixes dcp-masked (d) and dcp-encrypted (e) in the bucket dcp-athena.
    3. The last step in the workflow is to perform a crawler for each of these prefixes (f) and (g) by creating their respective tables in the AWS Glue Data Catalog.
  6. To enable fine-grained access to data, Lake Formation maps permissions to the tags you have configured. The implementation of this part is described further in this post.
  7. Athena can be used to query the data. Other tools, such as Amazon Redshift or Amazon Quicksight can also be used, as well as third-party tools.

If a user lacks permission to view sensitive data but needs to access it for machine learning model training purposes, AWS KMS can be used. The AWS KMS service manages the encryption keys that are used for data masking and to give access to the training algorithms. Users can see the masked data, but the algorithms can use the data in its original form to train the machine learning models.

This solution uses three personas:

secure-lf-admin: Data lake administrator. Responsible for configuring the data lake and assigning permissions to data administrators.
secure-lf-business-analyst: Business analyst. No access to certain confidential information.
secure-lf-data-scientist: Data scientist. No access to certain confidential information.

Solution implementation

To facilitate implementation, we created a CloudFormation template. The model and other artifacts produced can be found in this GitHub repository. You can use the CloudFormation dashboard to review the output of all the deployed features.

Choose the following Launch Stack button to deploy the CloudFormation template.

Select this image to open a link that starts building the CloudFormation stack

Deploy the CloudFormation template

To deploy the CloudFormation template and create the resources in your AWS account, follow the steps below.

  1. After signing in to the AWS account, deploy the CloudFormation template. On the Create stack window, choose Next.
    Figure 2: CloudFormation create stack screen

    Figure 2: CloudFormation create stack screen

  2. In the following section, enter a name for the stack. Enter a password in the TestUserPassword field for Lake Formation personas to use to sign in to the console. When finished filling in the fields, choose Next.
  3. On the next screen, review the selected options and choose Next.
  4. In the last section, review the information and select I acknowledge that AWS CloudFormation might create IAM resources with custom names. Choose Create Stack.
    Figure 3: List of parameters and values in the CloudFormation stack

    Figure 3: List of parameters and values in the CloudFormation stack

  5. Wait until the stack status changes to CREATE_COMPLETE.

The deployment process should take approximately 15 minutes to finish.

Run an AWS DMS task

To extract the data from the Amazon RDS instance, you must run an AWS DMS task. This makes the data available to Macie in an S3 bucket in Parquet format.

  1. Open the AWS DMS console.
  2. On the navigation bar, for the Migrate data option, select Database migration tasks.
  3. Select the task with the name rdstos3task.
  4. Choose Actions.
  5. Choose Restart/Resume. The loading process should take around 1 minute.

When the status changes to Load Complete, you will be able to see the migrated data in the target bucket (dcp-macie-<AWS_REGION>-<ACCOUNT_ID>) in the dataset folder. Within each prefix there will be a parquet file that follows the naming pattern: LOAD00000001.parquet. After this step, use Macie to scan the data for sensitive information in the files.

Run a classification job with Macie 

You must create a data classification job before you can evaluate the contents of the bucket. The job you create will run and evaluate the full contents of your S3 bucket to determine the files stored in the bucket contain PII. This job uses the managed identifiers available in Macie and a custom identifier.

  1. Open the Macie Console, on the navigation bar, select Jobs.
  2. Choose Create job.
  3. Select the S3 bucket dcp-macie-<AWS_REGION>-<ACCOUNT_ID> containing the output of the AWS DMS task. Choose Next to continue.
  4. On the Review Bucket page, verify the selected bucket is dcp-macie-<AWS_REGION>-<ACCOUNT_ID>, and then choose Next.
  5. In Refine the scope, create a new job with the following scope:
    1. Sensitive data Discovery options: One-time job (for demonstration purposes, this will be a single discovery job. For production environments, we recommend selecting the Scheduled job option, so Macie can analyze objects following a scheduled).
    2. Sampling Depth: 100 percent.
    3. Leave the other settings at their default values.
  6. On Managed data identifiers options, select All so Macie can use all managed data identifiers. This enables a set of built-in criteria to detect all identified types of sensitive data. Choose Next.
  7. On the Custom data identifiers option, select account_number, and then choose Next. With the custom identifier, you can create custom business logic to look for certain patterns in files stored in Amazon S3. In this example, the task generates a discovery job for files that contain data with the following regular expression format XYZ- followed by numbers, which is the default format of the false account_number generated in the dataset. The logic used for creating this custom data identifier is included in the CloudFormation template file.
  8. On the Select allow lists, choose Next to continue.
  9. Enter a name and description for the job.
  10. Choose Next to continue.
  11. On Review and create step, check the details of the job you created and choose Submit.
    Figure 4: List of Macie findings detected by the solution

    Figure 4: List of Macie findings detected by the solution

The amount of data being scanned directly influences how long the job takes to run. You can choose the Update button at the top of the screen, as shown in Figure 4, to see the updated status of the job. This job, based on the size of the test dataset, will take about 10 minutes to complete.

Run the AWS Glue data transformation pipeline

After the Macie job is finished, the discovery results are ingested into the bucket dcp-glue-<AWS_REGION>-<ACCOUNT_ID>, invoking the AWS Glue step of the workflow (dcp-Workflow), which should take approximately 11 minutes to complete.

To check the workflow progress:

  1. Open the AWS Glue console and on navigation bar, select Workflows (orchestration).
  2. Next, choose dcp-workflow.
  3. Next, select History to see the past runs of the dcp-workflow.

The AWS Glue job, which is launched as part of the workflow (dcp-workflow), reads the Macie findings to know the exact location of sensitive data. For example, in the customer table are name and birthdate. In the bank table are account_number, iban, and bban. And in the card table are card_number, card_expiration, and card_security_code. After this data is found, the job masks and encrypts the information.

Text encryption is done using an AWS KMS key. Here is the code snippet that provides this functionality:

def encrypt_rows(r):
    encrypted_entities = columns_to_be_masked_and_encrypted
    try:
        for entity in encrypted_entities:
            if entity in table_columns:
                encrypted_entity = get_kms_encryption(r[entity])
                r[entity + '_encrypted'] = encrypted_entity.decode("utf-8")
                del r[entity]
    except:
        print ("DEBUG:",sys.exc_info())
    return r

def get_kms_encryption(row):
    # Create a KMS client
    session = boto3.session.Session()
    client = session.client(service_name='kms',region_name=region_name)
   
    try:
        encryption_result = client.encrypt(KeyId=key_id, Plaintext=row)
        blob = encryption_result['CiphertextBlob']
        encrypted_row = base64.b64encode(blob)       
        return encrypted_row
       
    except:
        return 'Error on get_kms_encryption function'

If your application requires access to the unencrypted text, and because access to the AWS KMS encryption key exists, you can use the following excerpt example to access the information:

client.decrypt(CiphertextBlob=base64.b64decode(data_encrypted))
print(decrypted['Plaintext'])

After performing all the above steps, the datasets are fully anonymized with tables created in Data Catalog and data stored in the respective S3 buckets. These are the buckets where fine-grained access controls are applied through Lake Formation:

  • Masked data — s3://dcp-athena-<AWS_REGION>-<ACCOUNT_ID>/masked/
  • Encrypted data — s3://dcp-athena-<AWS_REGION>-<ACCOUNT_ID>/encrypted/

Now that the tables are defined, you refine the permissions using Lake Formation.

Enable Lake Formation fine-grained access

After the data is processed and stored, you use Lake Formation to define and enforce fine-grained access permissions and provide secure access to data analysts and data scientists.

To enable fine-grained access, you first add a user (secure-lf-admin) to Lake Formation:

  1. In the Lake Formation console, clear Add myself and select Add other AWS users or roles.
  2. From the drop-down menu, select secure-lf-admin.
  3. Choose Get started.
    Figure 5: Lake Formation deployment process

    Figure 5: Lake Formation deployment process

Grant access to different personas

Before you grant permissions to different user personas, you must register Amazon S3 locations in Lake Formation so that the personas can access the data. All buckets have been created with the following pattern <prefix>-<bucket_name>-<aws_region>-<account_id>, where <prefix> matches the prefix you selected when you deployed the Cloudformation template and <aws_region> corresponds to the selected AWS Region (for example, ap-southeast-1), and <account_id> is the 12 numbers that match your AWS account (for example, 123456789012). For ease of reading, we left only the initial part of the bucket name in the following instructions.

  1. In the Lake Formation console, on the navigation bar, on the Register and ingest option, select Data Lake locations.
  2. Choose Register location.
  3. Select the dcp-glue bucket and choose Register Location.
  4. Repeat for the dcp-macie/dataset, dcp-athena/masked, and dcp-athena/encrypted prefixes.
    Figure 6: Amazon S3 locations registered in the solution

    Figure 6: Amazon S3 locations registered in the solution

You’re now ready to grant access to different users.

Granting per-user granular access

After successfully deploying the AWS services described in the CloudFormation template, you must configure access to resources that are part of the proposed solution.

Grant read-only accesses to all tables for secure-lf-admin

Before proceeding you must sign in as the secure-lf-admin user. To do this, sign out from the AWS console and sign in again using the secure-lf-admin credential and password that you set in the CloudFormation template.

Now that you’re signed in as the user who administers the data lake, you can grant read-only access to all tables in the dataset database to the secure-lf-admin user.

  1. In the Permissions section, select Data Lake permissions, and then choose Grant.
  2. Select IAM users and roles.
  3. Select the secure-lf-admin user.
  4. Under LF-Tags or catalog resources, select Named data catalog resources.
  5. Select the database dataset.
  6. For Tables, select All tables.
  7. In the Table permissions section, select Alter and Super.
  8. Under Grantable permissions, select Alter and Super.
  9. Choose Grant.

You can confirm your user permissions on the Data Lake permissions page.

Create tags to grant access

Return to the Lake Formation console to define tag-based access control for users. You can assign policy tags to Data Catalog resources (databases, tables, and columns) to control access to this type of resources. Only users who receive the corresponding Lake Formation tag (and those who receive access with the resource method named) can access the resources.

  1. Open the Lake Formation console, then on the navigation bar, under Permissions, select LF-tags.
  2. Choose Add LF Tag. In the dialog box Add LF-tag, for Key, enter data, and for Values, enter mask. Choose Add, and then choose Add LF-Tag.
  3. Follow the same steps to add a second tag. For Key, enter segment, and for Values enter campaign.

Assign tags to users and databases

Now grant read-only access to the masked data to the secure-lf-data-scientist user.

  1. In the Lake Formation console, on the navigation bar, under Permissions, select Data Lake permissions. 
  2. Choose Grant.
  3. Under IAM users and roles, select secure-lf-data-scientist as the user.
  4. In the LF-Tags or catalog resources section, select Resources matched by LF-Tags and choose add LF-Tag. For Key, enter data and for Values, enter mask.
    Figure 7: Creating resource tags for Lake Formation

    Figure 7: Creating resource tags for Lake Formation

  5. In the section Database permissions, in the Database permissions part and in Grantable permissions, select Describe.
  6. In the section Table permissions, in the Table permissions part and in Grantable permissions, select Select.
  7. Choose Grant.
    Figure 8: Database and table permissions granted

    Figure 8: Database and table permissions granted

To complete the process and give the secure-lf-data-scientist user access to the dataset_masked database, you must assign the tag you created to the database.

  1. On the navigation bar, under Data Catalog, select Databases.
  2. Select dataset_masked and select Actions. From the drop-down menu, select Edit LF-Tags.
  3. In the section Edit LF-Tags: dataset_masked, choose Assign new LF-Tag. For Key, enter data, and for Values, enter mask. Choose Save.

Grant read-only accesses to secure-lf-business-analyst

Now grant the secure-lf-business-analyst user read-only access to certain encrypted columns using column-based permissions.

  1. In the Lake Formation console, under Data Catalog, select Databases.
  2. Select the database dataset_encrypted and then select Actions. From the drop-down menu, choose Grant.
  3. Select IAM users and roles.
  4. Choose secure-lf-business-analyst.
  5. In the LF-Tags or catalog resources section, select Named data catalog resources.
  6. In the Database permissions section, in the Database permissions section and in Grantable permissions, select Describe and Alter.
  7. Choose Grant.

Now give the secure-lf-business-analyst user access to the Customer table, except for the username column.

  1. In the Lake Formation console, under Data Catalog, select Databases.
  2. Select the database dataset_encrypted and then, choose View tables.
  3. From the Actions option in the drop-down menu, select Grant.
  4. Select IAM users and roles.
  5. Select secure-lf-business-analyst.
  6. In the LF-Tags or catalog resources part, select Named data catalog resources.
  7. In the Database section, leave the dataset_encrypted selected.
  8. In the tables section, select the customer table.
  9. In the Table permission section, in the Table permission section and in Grantable permissions, choose Select.
  10. In the Data Permissions section, select Column-based access.
  11. Select Include columns and select the id, username, mail, and gender columns, which are the data-less columns encrypted for the secure-lf-business-analyst user to have access to.
  12. Choose Grant.
    Figure 9: Granting access to secure-lf-business-analyst user in the Customer table

    Figure 9: Granting access to secure-lf-business-analyst user in the Customer table

Now give the secure-lf-business-analyst user access to the table Card, only for columns that do not contain PII information.

  1. In the Lake Formation console, under Data Catalog, choose Databases.
  2. Select the database dataset_encrypted and choose View tables.
  3. Select the table Card.
  4. In the Schema section, choose Edit schema.
  5. Select the cred_card_provider column, which is the column that has no PII data.
  6. Choose Edit tags.
  7. Choose Assign new LF-Tag.
  8. For Assigned keys, enter segment and for Values, enter mask.
    Figure 10: Editing tags in Lake Formation tables

    Figure 10: Editing tags in Lake Formation tables

  9. Choose Save, and then choose Save as new version.

In this step you add the segment tag in the column cred_card_provider to the card table. For the user secure-lf-business-analyst to have access, you need to configure this tag for the user.

  1. In the Lake Formation console, under Permissions, select Data Lake permissions.
  2. Choose Grant.
  3. Under IAM users and roles, select secure-lf-business-analyst as the user.
  4. In the LF-Tags or catalog resources section, select Resources matched by LF-Tags, and choose add LF-tag and for as Key enter segment and for Values, enter campaign.
    Figure 11: Configure tag-based access for user secure-lf-business-analyst

    Figure 11: Configure tag-based access for user secure-lf-business-analyst

  5. In the Database permissions section, in the Database permissions part and in Grantable permissions, select Describe from both options.
  6. In the Table permission section, in the Table permission part as well as in Grantable permissions, choose Select.
  7. Choose Grant.

The next step is to revoke Super access to the IAMAllowedPrincipals group.

The IAMAllowedPrincipals group includes all IAM users and roles that are allowed access to Data Catalog resources using IAM policies. The Super permission allows a principal to perform all operations supported by Lake Formation on the database or table on which it is granted. These settings provide access to Data Catalog resources and Amazon S3 locations controlled exclusively by IAM policies. Therefore, the individual permissions configured by Lake Formation are not considered, so you will remove the concessions already configured by the IAMAllowedPrincipals group, leaving only the Lake Formation settings.

  1. In the Databases menu, select the database dataset, and then select Actions. From the drop-down menu, select Revoke.
  2. In the Principals section, select IAM users and roles, and then select the IAMAllowedPrincipals group as the user.
  3. Under LF-Tags or catalog resources, select Named data catalog resources.
  4. In the Database section, leave the dataset option selected.
  5. Under Tables, select the following tables: bank, card, and customer.
  6. In the Table permissions section, select Super.
  7. Choose Revoke.

Repeat the same steps for the dataset_encrypted and dataset_masked databases.

Figure 12: Revoke SUPER access to the IAMAllowedPrincipals group

Figure 12: Revoke SUPER access to the IAMAllowedPrincipals group

You can confirm all user permissions on the Data Permissions page.

Querying the data lake using Athena with different personas

To validate the permissions of different personas, you use Athena to query the Amazon S3 data lake.

Ensure the query result location has been created as part of the CloudFormation stack (secure-athena-query-<ACCOUNT_ID>-<AWS_REGION>).

  1. Sign in to the Athena console with secure-lf-admin (use the password value for TestUserPassword from the CloudFormation stack) and verify that you are in the AWS Region used in the query result location.
  2. On the navigation bar, choose Query editor.
  3. Choose Setting to set up a query result location in Amazon S3, and then choose Browse S3 and select the bucket secure-athena-query-<ACCOUNT_ID>-<AWS_REGION>.
  4. Run a SELECT query on the dataset.
    SELECT * FROM "dataset"."bank" limit 10;

The secure-lf-admin user should see all tables in the dataset database and dcp. As for the banks dataset_encrypted and dataset_masked, the user should not have access to the tables.

Figure 13: Athena console with query results in clear text

Figure 13: Athena console with query results in clear text

Finally, validate the secure-lf-data-scientist permissions.

  1. Sign in to the Athena console with secure-lf-data-scientist (use the password value for TestUserPassword from the CloudFormation stack) and verify that you are in the correct Region.
  2. Run the following query:
    SELECT * FROM “dataset_masked”.”bank” limit 10;

The user secure-lf-data-scientist will only be able to view all the columns in the database dataset_masked.

Figure 14: Athena query results with masked data

Figure 14: Athena query results with masked data

Now, validate the secure-lf-business-analyst user permissions.

  1. Sign in to the Athena console as secure-lf-business-analyst (use the password value for TestUserPassword from the CloudFormation stack) and verify that you are in the correct Region.
  2. Run a SELECT query on the dataset.
    SELECT * FROM “dataset_encrypted”.”card” limit 10;

    Figure 15: Validating secure-lf-business-analyst user permissions to query data

    Figure 15: Validating secure-lf-business-analyst user permissions to query data

The user secure-lf-business-analyst should only be able to view the card and customer tables of the dataset_encrypted database. In the table card, you will only have access to the cred_card_provider column and in the table Customer, you will have access only in the username, mail, and sex columns, as previously configured in Lake Formation.

Cleaning up the environment

After testing the solution, remove the resources you created to avoid unnecessary expenses.

  1. Open the Amazon S3 console.
  2. Navigate to each of the following buckets and delete all the objects within:
    1. dcp-assets-<AWS_REGION>-<ACCOUNT_ID>
    2. dcp-athena-<AWS_REGION>-<ACCOUNT_ID>
    3. dcp-glue-<AWS_REGION>-<ACCOUNT_ID>
    4. dcp-macie-<AWS_REGION>-<ACCOUNT_ID>
  3. Open the CloudFormation console.
  4. Select the Stacks option from the navigation bar.
  5. Select the stack that you created in Deploy the CloudFormation Template.
  6. Choose Delete, and then choose Delete Stack in the pop-up window.
  7. If you also want to delete the bucket that was created, go to Amazon S3 and delete it from the console or by using the AWS CLI.
  8. To remove the settings made in Lake Formation, go to the Lake Formation dashboard, and remove the data lake locales and the Lake Formation administrator.

Conclusion 

Now that the solution is implemented, you have an automated anonymization dataflow. This solution demonstrates how you can build a solution using AWS serverless solutions where you only pay for what you use and without worrying about infrastructure provisioning. In addition, this solution is customizable to meet other data protection requirements such as General Data Protection Law (LGPD) in Brazil, General Data Protection Regulation in Europe (GDPR), and the Association of Banks in Singapore (ABS) Cloud Computing Implementation Guide.

We used Macie to identify the sensitive data stored in Amazon S3 and AWS Glue to generate Macie reports to anonymize the sensitive data found. Finally, we used Lake Formation to implement fine-grained data access control to specific information and demonstrated how you can programmatically grant access to applications that need to work with unmasked data.

Related links

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Iris Ferreira

Iris Ferreira

Iris is a solutions architect at AWS, supporting clients in their innovation and digital transformation journeys in the cloud. In her free time, she enjoys going to the beach, traveling, hiking and always being in contact with nature.

Paulo Aragão

Paulo Aragão

Paulo is a Principal Solutions Architect and supports clients in the financial sector to tread the new world of DeFi, web3.0, Blockchain, dApps, and Smart Contracts. In addition, he has extensive experience in high performance computing (HPC) and machine learning. Passionate about music and diving, he devours books, plays World of Warcraft and New World, and cooks for friends.

Leo da Silva

Leo da Silva

Leo is a Principal Security Solutions Architect at AWS and uses his knowledge to help customers better use cloud services and technologies securely. Over the years, he had the opportunity to work in large, complex environments, designing, architecting, and implementing highly scalable and secure solutions to global companies. He is passionate about football, BBQ, and Jiu Jitsu — the Brazilian version of them all.

Use Amazon Athena with Spark SQL for your open-source transactional table formats

Post Syndicated from Pathik Shah original https://aws.amazon.com/blogs/big-data/use-amazon-athena-with-spark-sql-for-your-open-source-transactional-table-formats/

AWS-powered data lakes, supported by the unmatched availability of Amazon Simple Storage Service (Amazon S3), can handle the scale, agility, and flexibility required to combine different data and analytics approaches. As data lakes have grown in size and matured in usage, a significant amount of effort can be spent keeping the data consistent with business events. To ensure files are updated in a transactionally consistent manner, a growing number of customers are using open-source transactional table formats such as Apache Iceberg, Apache Hudi, and Linux Foundation Delta Lake that help you store data with high compression rates, natively interface with your applications and frameworks, and simplify incremental data processing in data lakes built on Amazon S3. These formats enable ACID (atomicity, consistency, isolation, durability) transactions, upserts, and deletes, and advanced features such as time travel and snapshots that were previously only available in data warehouses. Each storage format implements this functionality in slightly different ways; for a comparison, refer to Choosing an open table format for your transactional data lake on AWS.

In 2023, AWS announced general availability for Apache Iceberg, Apache Hudi, and Linux Foundation Delta Lake in Amazon Athena for Apache Spark, which removes the need to install a separate connector or associated dependencies and manage versions, and simplifies the configuration steps required to use these frameworks.

In this post, we show you how to use Spark SQL in Amazon Athena notebooks and work with Iceberg, Hudi, and Delta Lake table formats. We demonstrate common operations such as creating databases and tables, inserting data into the tables, querying data, and looking at snapshots of the tables in Amazon S3 using Spark SQL in Athena.

Prerequisites

Complete the following prerequisites:

Download and import example notebooks from Amazon S3

To follow along, download the notebooks discussed in this post from the following locations:

After you download the notebooks, import them into your Athena Spark environment by following the To import a notebook section in Managing notebook files.

Navigate to specific Open Table Format section

If you are interested in Iceberg table format, navigate to Working with Apache Iceberg tables section.

If you are interested in Hudi table format, navigate to Working with Apache Hudi tables section.

If you are interested in Delta Lake table format, navigate to Working with Linux foundation Delta Lake tables section.

Working with Apache Iceberg tables

When using Spark notebooks in Athena, you can run SQL queries directly without having to use PySpark. We do this by using cell magics, which are special headers in a notebook cell that change the cell’s behavior. For SQL, we can add the %%sql magic, which will interpret the entire cell contents as a SQL statement to be run on Athena.

In this section, we show how you can use SQL on Apache Spark for Athena to create, analyze, and manage Apache Iceberg tables.

Set up a notebook session

In order to use Apache Iceberg in Athena, while creating or editing a session, select the Apache Iceberg option by expanding the Apache Spark properties section. It will pre-populate the properties as shown in the following screenshot.

This image shows the Apache Iceberg properties set while creating Spak session in Athena.

For steps, see Editing session details or Creating your own notebook.

The code used in this section is available in the SparkSQL_iceberg.ipynb file to follow along.

Create a database and Iceberg table

First, we create a database in the AWS Glue Data Catalog. With the following SQL, we can create a database called icebergdb:

%%sql
CREATE DATABASE icebergdb

Next, in the database icebergdb, we create an Iceberg table called noaa_iceberg pointing to a location in Amazon S3 where we will load the data. Run the following statement and replace the location s3://<your-S3-bucket>/<prefix>/ with your S3 bucket and prefix:

%%sql
CREATE TABLE icebergdb.noaa_iceberg(
station string,
date string,
latitude string,
longitude string,
elevation string,
name string,
temp string,
temp_attributes string,
dewp string,
dewp_attributes string,
slp string,
slp_attributes string,
stp string,
stp_attributes string,
visib string,
visib_attributes string,
wdsp string,
wdsp_attributes string,
mxspd string,
gust string,
max string,
max_attributes string,
min string,
min_attributes string,
prcp string,
prcp_attributes string,
sndp string,
frshtt string)
USING iceberg
PARTITIONED BY (year string)
LOCATION 's3://<your-S3-bucket>/<prefix>/noaaiceberg/'

Insert data into the table

To populate the noaa_iceberg Iceberg table, we insert data from the Parquet table sparkblogdb.noaa_pq that was created as part of the prerequisites. You can do this using an INSERT INTO statement in Spark:

%%sql
INSERT INTO icebergdb.noaa_iceberg select * from sparkblogdb.noaa_pq

Alternatively, you can use CREATE TABLE AS SELECT with the USING iceberg clause to create an Iceberg table and insert data from a source table in one step:

%%sql
CREATE TABLE icebergdb.noaa_iceberg
USING iceberg
PARTITIONED BY (year)
AS SELECT * FROM sparkblogdb.noaa_pq

Query the Iceberg table

Now that the data is inserted in the Iceberg table, we can start analyzing it. Let’s run a Spark SQL to find the minimum recorded temperature by year for the 'SEATTLE TACOMA AIRPORT, WA US' location:

%%sql
select name, year, min(MIN) as minimum_temperature
from icebergdb.noaa_iceberg
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

We get following output.

Image shows output of first select query

Update data in the Iceberg table

Let’s look at how to update data in our table. We want to update the station name 'SEATTLE TACOMA AIRPORT, WA US' to 'Sea-Tac'. Using Spark SQL, we can run an UPDATE statement against the Iceberg table:

%%sql
UPDATE icebergdb.noaa_iceberg
SET name = 'Sea-Tac'
WHERE name = 'SEATTLE TACOMA AIRPORT, WA US'

We can then run the previous SELECT query to find the minimum recorded temperature for the 'Sea-Tac' location:

%%sql
select name, year, min(MIN) as minimum_temperature
from icebergdb.noaa_iceberg
where name = 'Sea-Tac'
group by 1,2

We get the following output.

Image shows output of second select query

Compact data files

Open table formats like Iceberg work by creating delta changes in file storage, and tracking the versions of rows through manifest files. More data files leads to more metadata stored in manifest files, and small data files often cause an unnecessary amount of metadata, resulting in less efficient queries and higher Amazon S3 access costs. Running Iceberg’s rewrite_data_files procedure in Spark for Athena will compact data files, combining many small delta change files into a smaller set of read-optimized Parquet files. Compacting files speeds up the read operation when queried. To run compaction on our table, run the following Spark SQL:

%%sql
CALL spark_catalog.system.rewrite_data_files
(table => 'icebergdb.noaa_iceberg', strategy=>'sort', sort_order => 'zorder(name)')

rewrite_data_files offers options to specify your sort strategy, which can help reorganize and compact data.

List table snapshots

Each write, update, delete, upsert, and compaction operation on an Iceberg table creates a new snapshot of a table while keeping the old data and metadata around for snapshot isolation and time travel. To list the snapshots of an Iceberg table, run the following Spark SQL statement:

%%sql
SELECT *
FROM spark_catalog.icebergdb.noaa_iceberg.snapshots

Expire old snapshots

Regularly expiring snapshots is recommended to delete data files that are no longer needed, and to keep the size of table metadata small. It will never remove files that are still required by a non-expired snapshot. In Spark for Athena, run the following SQL to expire snapshots for the table icebergdb.noaa_iceberg that are older than a specific timestamp:

%%sql
CALL spark_catalog.system.expire_snapshots
('icebergdb.noaa_iceberg', TIMESTAMP '2023-11-30 00:00:00.000')

Note that the timestamp value is specified as a string in format yyyy-MM-dd HH:mm:ss.fff. The output will give a count of the number of data and metadata files deleted.

Drop the table and database

You can run the following Spark SQL to clean up the Iceberg tables and associated data in Amazon S3 from this exercise:

%%sql
DROP TABLE icebergdb.noaa_iceberg PURGE

Run the following Spark SQL to remove the database icebergdb:

%%sql
DROP DATABASE icebergdb

To learn more about all the operations you can perform on Iceberg tables using Spark for Athena, refer to Spark Queries and Spark Procedures in the Iceberg documentation.

Working with Apache Hudi tables

Next, we show how you can use SQL on Spark for Athena to create, analyze, and manage Apache Hudi tables.

Set up a notebook session

In order to use Apache Hudi in Athena, while creating or editing a session, select the Apache Hudi option by expanding the Apache Spark properties section.

This image shows the Apache Hudi properties set while creating Spak session in Athena.

For steps, see Editing session details or Creating your own notebook.

The code used in this section should be available in the SparkSQL_hudi.ipynb file to follow along.

Create a database and Hudi table

First, we create a database called hudidb that will be stored in the AWS Glue Data Catalog followed by Hudi table creation:

%%sql
CREATE DATABASE hudidb

We create a Hudi table pointing to a location in Amazon S3 where we will load the data. Note that the table is of copy-on-write type. It is defined by type= 'cow' in the table DDL. We have defined station and date as the multiple primary keys and preCombinedField as year. Also, the table is partitioned on year. Run the following statement and replace the location s3://<your-S3-bucket>/<prefix>/ with your S3 bucket and prefix:

%%sql
CREATE TABLE hudidb.noaa_hudi(
station string,
date string,
latitude string,
longitude string,
elevation string,
name string,
temp string,
temp_attributes string,
dewp string,
dewp_attributes string,
slp string,
slp_attributes string,
stp string,
stp_attributes string,
visib string,
visib_attributes string,
wdsp string,
wdsp_attributes string,
mxspd string,
gust string,
max string,
max_attributes string,
min string,
min_attributes string,
prcp string,
prcp_attributes string,
sndp string,
frshtt string,
year string)
USING HUDI
PARTITIONED BY (year)
TBLPROPERTIES(
primaryKey = 'station, date',
preCombineField = 'year',
type = 'cow'
)
LOCATION 's3://<your-S3-bucket>/<prefix>/noaahudi/'

Insert data into the table

Like with Iceberg, we use the INSERT INTO statement to populate the table by reading data from the sparkblogdb.noaa_pq table created in the previous post:

%%sql
INSERT INTO hudidb.noaa_hudi select * from sparkblogdb.noaa_pq

Query the Hudi table

Now that the table is created, let’s run a query to find the maximum recorded temperature for the 'SEATTLE TACOMA AIRPORT, WA US' location:

%%sql
select name, year, max(MAX) as maximum_temperature
from hudidb.noaa_hudi
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

Update data in the Hudi table

Let’s change the station name 'SEATTLE TACOMA AIRPORT, WA US' to 'Sea–Tac'. We can run an UPDATE statement on Spark for Athena to update the records of the noaa_hudi table:

%%sql
UPDATE hudidb.noaa_hudi
SET name = 'Sea-Tac'
WHERE name = 'SEATTLE TACOMA AIRPORT, WA US'

We run the previous SELECT query to find the maximum recorded temperature for the 'Sea-Tac' location:

%%sql
select name, year, max(MAX) as maximum_temperature
from hudidb.noaa_hudi
where name = 'Sea-Tac'
group by 1,2

Run time travel queries

We can use time travel queries in SQL on Athena to analyze past data snapshots. For example:

%%sql
select name, year, max(MAX) as maximum_temperature
from hudidb.noaa_hudi timestamp as of '2023-12-01 23:53:43.100'
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

This query checks the Seattle Airport temperature data as of a specific time in the past. The timestamp clause lets us travel back without altering current data. Note that the timestamp value is specified as a string in format yyyy-MM-dd HH:mm:ss.fff.

Optimize query speed with clustering

To improve query performance, you can perform clustering on Hudi tables using SQL in Spark for Athena:

%%sql
CALL run_clustering(table => 'hudidb.noaa_hudi', order => 'name')

Compact tables

Compaction is a table service employed by Hudi specifically in Merge On Read (MOR) tables to merge updates from row-based log files to the corresponding columnar-based base file periodically to produce a new version of the base file. Compaction is not applicable to Copy On Write (COW) tables and only applies to MOR tables. You can run the following query in Spark for Athena to perform compaction on MOR tables:

%%sql
CALL run_compaction(op => 'run', table => 'hudi_table_mor');

Drop the table and database

Run the following Spark SQL to remove the Hudi table you created and associated data from the Amazon S3 location:

%%sql
DROP TABLE hudidb.noaa_hudi PURGE

Run the following Spark SQL to remove the database hudidb:

%%sql
DROP DATABASE hudidb

To learn about all the operations you can perform on Hudi tables using Spark for Athena, refer to SQL DDL and Procedures in the Hudi documentation.

Working with Linux foundation Delta Lake tables

Next, we show how you can use SQL on Spark for Athena to create, analyze, and manage Delta Lake tables.

Set up a notebook session

In order to use Delta Lake in Spark for Athena, while creating or editing a session, select Linux Foundation Delta Lake by expanding the Apache Spark properties section.

This image shows the Delta Lake properties set while creating Spak session in Athena.

For steps, see Editing session details or Creating your own notebook.

The code used in this section should be available in the SparkSQL_delta.ipynb file to follow along.

Create a database and Delta Lake table

In this section, we create a database in the AWS Glue Data Catalog. Using following SQL, we can create a database called deltalakedb:

%%sql
CREATE DATABASE deltalakedb

Next, in the database deltalakedb, we create a Delta Lake table called noaa_delta pointing to a location in Amazon S3 where we will load the data. Run the following statement and replace the location s3://<your-S3-bucket>/<prefix>/ with your S3 bucket and prefix:

%%sql
CREATE TABLE deltalakedb.noaa_delta(
station string,
date string,
latitude string,
longitude string,
elevation string,
name string,
temp string,
temp_attributes string,
dewp string,
dewp_attributes string,
slp string,
slp_attributes string,
stp string,
stp_attributes string,
visib string,
visib_attributes string,
wdsp string,
wdsp_attributes string,
mxspd string,
gust string,
max string,
max_attributes string,
min string,
min_attributes string,
prcp string,
prcp_attributes string,
sndp string,
frshtt string)
USING delta
PARTITIONED BY (year string)
LOCATION 's3://<your-S3-bucket>/<prefix>/noaadelta/'

Insert data into the table

We use an INSERT INTO statement to populate the table by reading data from the sparkblogdb.noaa_pq table created in the previous post:

%%sql
INSERT INTO deltalakedb.noaa_delta select * from sparkblogdb.noaa_pq

You can also use CREATE TABLE AS SELECT to create a Delta Lake table and insert data from a source table in one query.

Query the Delta Lake table

Now that the data is inserted in the Delta Lake table, we can start analyzing it. Let’s run a Spark SQL to find the minimum recorded temperature for the 'SEATTLE TACOMA AIRPORT, WA US' location:

%%sql
select name, year, max(MAX) as minimum_temperature
from deltalakedb.noaa_delta
where name = 'SEATTLE TACOMA AIRPORT, WA US'
group by 1,2

Update data in the Delta lake table

Let’s change the station name 'SEATTLE TACOMA AIRPORT, WA US' to 'Sea–Tac'. We can run an UPDATE statement on Spark for Athena to update the records of the noaa_delta table:

%%sql
UPDATE deltalakedb.noaa_delta
SET name = 'Sea-Tac'
WHERE name = 'SEATTLE TACOMA AIRPORT, WA US'

We can run the previous SELECT query to find the minimum recorded temperature for the 'Sea-Tac' location, and the result should be the same as earlier:

%%sql
select name, year, max(MAX) as minimum_temperature
from deltalakedb.noaa_delta
where name = 'Sea-Tac'
group by 1,2

Compact data files

In Spark for Athena, you can run OPTIMIZE on the Delta Lake table, which will compact the small files into larger files, so the queries are not burdened by the small file overhead. To perform the compaction operation, run the following query:

%%sql
OPTIMIZE deltalakedb.noaa_delta

Refer to Optimizations in the Delta Lake documentation for different options available while running OPTIMIZE.

Remove files no longer referenced by a Delta Lake table

You can remove files stored in Amazon S3 that are no longer referenced by a Delta Lake table and are older than the retention threshold by running the VACCUM command on the table using Spark for Athena:

%%sql
VACUUM deltalakedb.noaa_delta

Refer to Remove files no longer referenced by a Delta table in the Delta Lake documentation for options available with VACUUM.

Drop the table and database

Run the following Spark SQL to remove the Delta Lake table you created:

%%sql
DROP TABLE deltalakedb.noaa_delta

Run the following Spark SQL to remove the database deltalakedb:

%%sql
DROP DATABASE deltalakedb

Running DROP TABLE DDL on the Delta Lake table and database deletes the metadata for these objects, but doesn’t automatically delete the data files in Amazon S3. You can run the following Python code in the notebook’s cell to delete the data from the S3 location:

import boto3

s3 = boto3.resource('s3')
bucket = s3.Bucket('<your-S3-bucket>')
bucket.objects.filter(Prefix="<prefix>/noaadelta/").delete()

To learn more about the SQL statements that you can run on a Delta Lake table using Spark for Athena, refer to the quickstart in the Delta Lake documentation.

Conclusion

This post demonstrated how to use Spark SQL in Athena notebooks to create databases and tables, insert and query data, and perform common operations like updates, compactions, and time travel on Hudi, Delta Lake, and Iceberg tables. Open table formats add ACID transactions, upserts, and deletes to data lakes, overcoming limitations of raw object storage. By removing the need to install separate connectors, Spark on Athena’s built-in integration reduces configuration steps and management overhead when using these popular frameworks for building reliable data lakes on Amazon S3. To learn more about selecting an open table format for your data lake workloads, refer to Choosing an open table format for your transactional data lake on AWS.


About the Authors

Pathik Shah is a Sr. Analytics Architect on Amazon Athena. He joined AWS in 2015 and has been focusing in the big data analytics space since then, helping customers build scalable and robust solutions using AWS analytics services.

Raj Devnath is a Product Manager at AWS on Amazon Athena. He is passionate about building products customers love and helping customers extract value from their data. His background is in delivering solutions for multiple end markets, such as finance, retail, smart buildings, home automation, and data communication systems.

How to build a unified authorization layer for identity providers with Amazon Verified Permissions

Post Syndicated from Akash Kumar original https://aws.amazon.com/blogs/security/how-to-build-a-unified-authorization-layer-for-identity-providers-with-amazon-verified-permissions/

Enterprises often have an identity provider (IdP) for their employees and another for their customers. Using multiple IdPs allows you to apply different access controls and policies for employees and for customers. However, managing multiple identity systems can be complex. A unified authorization layer can ease administration by centralizing access policies for APIs regardless of the user’s IdP. The authorization layer evaluates access tokens from any authorized IdP before allowing API access. This removes authorization logic from the APIs and simplifies specifying organization-wide policies. Potential drawbacks include additional complexity in the authorization layer. However, simplifying the management of policies reduces cost of ownership and the likelihood of errors.

Consider a veterinary clinic that has an IdP for their employees. Their clients, the pet owners, would have a separate IdP. Employees might have different sign-in requirements than the clients. These requirements could include features such as multi-factor authentication (MFA) or additional auditing functionality. Applying identical access controls for clients may not be desirable. The clinic’s scheduling application would manage access from both the clinic employees and pet owners. By implementing a unified authorization layer, the scheduling app doesn’t need to be aware of the different IdPs or tokens. The authorization layer handles evaluating tokens and applying policies, such as allowing the clinic employees full access to appointment data while limiting pet owners to just their pet’s records. In this post, we show you an architecture for this situation that demonstrates how to build a unified authorization layer using multiple Amazon Cognito user pools, Amazon Verified Permissions, and an AWS Lambda authorizer for Amazon API Gateway-backed APIs.

In the architecture, API Gateway exposes APIs to provide access to backend resources. API Gateway is a fully-managed service that allows developers to build APIs that act as an entry point for applications. To integrate API Gateway with multiple IdPs, you can use a Lambda authorizer to control access to the API. The IdP in this architecture is Amazon Cognito, which provides the authentication function for users before they’re authorized by Verified Permissions, which implements fine-grained authorization on resources in an application. Keep in mind that Verified Permissions has limits on policy sizes and requests per second. Large deployments might require a different policy store or a caching layer. The four services work together to combine multiple IdPs into a unified authorization layer. The architecture isn’t limited to the Cognito IdP — third-party IdPs that generate JSON Web Tokens (JWTs) can be used, including combinations of different IdPs.

Architecture overview

This sample architecture relies on user-pool multi-tenancy for user authentication. It uses Cognito user pools to assign authenticated users a set of temporary and least-privilege credentials for application access. Once users are authenticated, they are authorized to access backend functions via a Lambda Authorizer function. This function interfaces with Verified Permissions to apply the appropriate access policy based on user attributes.

This sample architecture is based on the scenario of an application that has two sets of users: an internal set of users, veterinarians, as well as an external set of users, clients, with each group having specific access to the API. Figure 1 shows the user request flow.

Figure 1: User request flow

Figure 1: User request flow

Let’s go through the request flow to understand what happens at each step, as shown in Figure 1:

  1. There two groups of users — External (Clients) and Internal (Veterinarians). These user groups sign in through a web portal that authenticates against an IdP (Amazon Cognito).
  2. The groups attempt to access the get appointment API through API Gateway, along with their JWT tokens with claims and client ID.
  3. The Lambda authorizer validates the claims.

    Note: If Cognito is the IdP, then Verified Permissions can authorize the user from their JWT directly with the IsAuthorizedWithToken API.

  4. After validating the JWT token, the Lambda authorizer makes a query to Verified Permissions with associated policy information to check the request.
  5. API Gateway evaluates the policy that the Lambda authorizer returned, to allow or deny access to the resource.
  6. If allowed, API Gateway accesses the resource. If denied, API Gateway returns a 403 Forbidden error.

Note: To further optimize the Lambda authorizer, the authorization decision can be cached or disabled, depending on your needs. By enabling caching, you can improve the performance, because the authorization policy will be returned from the cache whenever there is a cache key match. To learn more, see Configure a Lambda authorizer using the API Gateway console.

Walkthrough

This walkthrough demonstrates the preceding scenario for an authorization layer supporting veterinarians and clients. Each set of users will have their own distinct Amazon Cognito user pool.

Verified Permissions policies associated with each Cognito pool enforce access controls. In the veterinarian pool, veterinarians are only allowed to access data for their own patients. Similarly, in the client pool, clients are only able to view and access their own data. This keeps data properly segmented and secured between veterinarians and clients.

Internal policy

permit (principal in UserGroup::"AllVeterinarians",
   action == Action::"GET/appointment",
   resource in UserGroup::"AllVeterinarians")
   when {principal == resource.Veterinarian };

External policy

permit (principal in UserGroup::"AllClients",
   action == Action::"GET/appointment",
   resource in UserGroup::"AllClients")
   when {principal == resource.owner};

The example internal and external policies, along with Cognito serving as an IdP, allow the veterinarian users to federate in to the application through one IdP, while the external clients must use another IdP. This, coupled with the associated authorization policies, allows you to create and customize fine-grained access policies for each user group.

To validate the access request with the policy store, the Lambda authorizer execution role also requires the verifiedpermissions:IsAuthorized action.

Although our example Verified Permissions policies are relatively simple, Cedar policy language is extensive and allows you to define custom rules for your business needs. For example, you could develop a policy that allows veterinarians to access client records only during the day of the client’s appointment.

Implement the sample architecture

The architecture is based on a user-pool multi-tenancy for user authentication. It uses Amazon Cognito user pools to assign authenticated users a set of temporary and least privilege credentials for application access. After users are authenticated, they are authorized to access APIs through a Lambda function. This function interfaces with Verified Permissions to apply the appropriate access policy based on user attributes.

Prerequisites

You need the following prerequisites:

  • The AWS Command Line Interface (CLI) installed and configured for use.
  • Python 3.9 or later, to package Python code for Lambda.

    Note: We recommend that you use a virtual environment or virtualenvwrapper to isolate the sample from the rest of your Python environment.

  • An AWS Identity and Access Management (IAM) role or user with enough permissions to create an Amazon Cognito user pool, IAM role, Lambda function, IAM policy, and API Gateway instance.
  • jq for JSON processing in bash script.

    To install on Ubuntu/Debian, use the following command:

    sudo apt-get install jq

    To install on Mac with Homebrew, using the following command:

    brew install jq

  • The GitHub repository for the sample. You can download it, or you can use the following Git command to download it from your terminal.

    Note: This sample code should be used to test the solution and is not intended to be used in a production account.

    $ git clone https://github.com/aws-samples/amazon-cognito-avp-apigateway.git
    $ cd amazon-cognito-avp-apigateway

To implement this reference architecture, you will use the following services:

  • Amazon Verified Permissions is a service that helps you implement and enforce fine-grained authorization on resources within the applications that you build and deploy, such as HR systems and banking applications.
  • Amazon API Gateway is a fully managed service that developers can use to create, publish, maintain, monitor, and secure APIs at any scale.
  • AWS Lambda is a serverless compute service that lets you run code without provisioning or managing servers, creating workload-aware cluster scaling logic, maintaining event integrations, or managing runtimes.
  • Amazon Cognito provides an identity store that scales to millions of users, supports social and enterprise identity federation, and offers advanced security features to protect your consumers and business.

Note: We tested this architecture in the us-east-1 AWS Region. Before you select a Region, verify that the necessary services — Amazon Verified Permissions, Amazon Cognito, API Gateway, and Lambda — are available in those Regions.

Deploy the sample architecture

From within the directory where you downloaded the sample code from GitHub, first run the following command to package the Lambda functions. Then run the next command to generate a random Cognito user password and create the resources described in the previous section.

Note: In this case, you’re generating a random user password for demonstration purposes. Follow best practices for user passwords in production implementations.

$ bash ./helper.sh package-lambda-functions
 …
Successfully completed packaging files.
$ bash ./helper.sh cf-create-stack-gen-password
 …
Successfully created CloudFormation stack.

Validate Cognito user creation

Run the following commands to open the Cognito UI in your browser and then sign in with your credentials. This validates that the previous commands created Cognito users successfully.

Note: When you run the commands, they return the username and password that you should use to sign in.

For internal user pool domain users

$ bash ./helper.sh open-cognito-internal-domain-ui
 Opening Cognito UI...
 URL: xxxxxxxxx
 Please use following credentials to login:
 Username: cognitouser
 Password: xxxxxxxx

For external user pool domain users

$ bash ./helper.sh open-cognito-external-domain-ui
 Opening Cognito UI...
 URL: xxxxxxxxx
 Please use following credentials to login:
 Username: cognitouser
 Password: xxxxxxxx

Validate Cognito JWT upon sign in

Because you haven’t installed a web application that would respond to the redirect request, Cognito will redirect to localhost, which might look like an error. The key aspect is that after a successful sign-in, there is a URL similar to the following in the navigation bar of your browser.

http://localhost/#id_token=eyJraWQiOiJicVhMYWFlaTl4aUhzTnY3W...

Test the API configuration

Before you protect the API with Cognito so that only authorized users can access it, let’s verify that the configuration is correct and API Gateway serves the API. The following command makes a curl request to API Gateway to retrieve data from the API service.

$ bash ./helper.sh curl-api

API to check the appointment details of PI-T123
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123
Response: 
{"appointment": {"id": "PI-T123", "name": "Dave", "Pet": "Onyx - Dog. 2y 3m", "Phone Number": "+1234567", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Jane"}}

API to check the appointment details of PI-T124
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T124
Response: 
{"appointment": {"id": "PI-T124", "name": "Joy", "Pet": "Jelly - Dog. 6y 2m", "Phone Number": "+1368728", "Visit History": "None", "Assigned Veterinarian": "Jane"}}

API to check the appointment details of PI-T125
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T125
Response: 
{"appointment": {"id": "PI-T125", "name": "Dave", "Pet": "Sassy - Cat. 1y", "Phone Number": "+1398777", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Adam"}}

Protect the API

In the next step, you deploy a Verified Permissions policy store and a Lambda authorizer. The policy store contains the policies for user authorization. The Lambda authorizer verifies users’ access tokens and authorizes the users through Verified Permissions.

Update and create resources

Run the following command to update existing resources and create a Lambda authorizer and Verified Permissions policy store.

$ bash ./helper.sh cf-update-stack
 Successfully updated CloudFormation stack.

Test the custom authorizer setup

Begin your testing with the following request, which doesn’t include an access token.

Note: Wait for a few minutes to allow API Gateway to deploy before you run the following commands.

$ bash ./helper.sh curl-api
API to check the appointment details of PI-T123
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123
Response: 
{"message":"Unauthorized"}

API to check the appointment details of PI-T124
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T124
Response: 
{"message":"Unauthorized"}

API to check the appointment details of PI-T125
URL: https://epgst74zff.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T125
Response: 
{"message":"Unauthorized"}

The architecture denied the request with the message “Unauthorized.” At this point, API Gateway expects a header named Authorization (case sensitive) in the request. If there’s no authorization header, API Gateway denies the request before it reaches the Lambda authorizer. This is a way to filter out requests that don’t include required information.

Use the following command for the next test. In this test, you pass the required header, but the token is invalid because it wasn’t issued by Cognito and is instead a simple JWT-format token stored in ./helper.sh. To learn more about how to decode and validate a JWT, see Decode and verify a Cognito JSON token.

$ bash ./helper.sh curl-api-invalid-token
 {"Message":"User is not authorized to access this resource"}

This time the message is different. The Lambda authorizer received the request and identified the token as invalid and responded with the message “User is not authorized to access this resource.”

To make a successful request to the protected API, your code must perform the following steps:

  1. Use a user name and password to authenticate against your Cognito user pool.
  2. Acquire the tokens (ID token, access token, and refresh token).
  3. Make an HTTPS (TLS) request to API Gateway and pass the access token in the headers.

To finish testing, programmatically sign in to the Cognito UI, acquire a valid access token, and make a request to API Gateway. Run the following commands to call the protected internal and external APIs.

$ ./helper.sh curl-protected-internal-user-api

Getting API URL, Cognito Usernames, Cognito Users Password and Cognito ClientId...
User: Jane
Password: Pa%%word-2023-04-17-17-11-32
Resource: PI-T123
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"appointment": {"id": "PI-T123", "name": "Dave", "Pet": "Onyx - Dog. 2y 3m", "Phone Number": "+1234567", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Jane"}}

User: Adam
Password: Pa%%word-2023-04-17-17-11-32
Resource: PI-T123
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"Message":"User is not authorized to access this resource"}

User: Adam
Password: Pa%%word-2023-04-17-17-11-32
Resource: PI-T125
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T125

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"appointment": {"id": "PI-T125", "name": "Dave", "Pet": "Sassy - Cat. 1y", "Phone Number": "+1398777", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Adam"}}

Now calling external userpool users for accessing request

$ ./helper.sh curl-protected-external-user-api
User: Dave
Password: Pa%%word-2023-04-17-17-11-32
Resource: PI-T123
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"appointment": {"id": "PI-T123", "name": "Dave", "Pet": "Onyx - Dog. 2y 3m", "Phone Number": "+1234567", "Visit History": "Patient History from last visit with primary vet", "Assigned Veterinarian": "Jane"}}

User: Joy
Password Pa%%word-2023-04-17-17-11-32
Resource: PI-T123
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T123

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"Message":"User is not authorized to access this resource"}

User: Joy
Password Pa%%word-2023-04-17-17-11-32
Resource: PI-T124
URL: https://16qyz501mg.execute-api.us-east-1.amazonaws.com/dev/appointment/PI-T124

Authenticating to get access_token...
Access Token: eyJraWQiOiJIaVRvckxxxxxxxxxx6BfCBKASA

Response: 
{"appointment": {"id": "PI-T124", "name": "Joy", "Pet": "Jelly - Dog. 6y 2m", "Phone Number": "+1368728", "Visit History": "None", "Assigned Veterinarian": "Jane"}}

This time, you receive a response with data from the API service. Let’s recap the steps that the example code performed:

  1. The Lambda authorizer validates the access token.
  2. The Lambda authorizer uses Verified Permissions to evaluate the user’s requested actions against the policy store.
  3. The Lambda authorizer passes the IAM policy back to API Gateway.
  4. API Gateway evaluates the IAM policy, and the final effect is an allow.
  5. API Gateway forwards the request to Lambda.
  6. Lambda returns the response.

In each of the tests, internal and external, the architecture denied the request because the Verified Permissions policies denied access to the user. In the internal user pool, the policies only allow veterinarians to see their own patients’ data. Similarly, in the external user pool, the policies only allow clients to see their own data.

Clean up resources

Run the following command to delete the deployed resources and clean up.

$ bash ./helper.sh cf-delete-stack

Additional information

Verified Permissions is integrated with AWS CloudTrail, a service that provides a record of actions taken by a user, role, or AWS service in Verified Permissions. CloudTrail captures API calls for Verified Permissions as events. You can choose to capture actions performed on a Verified Permissions policy store by the Lambda authorizer. Verified Permissions logs can also be injected into your security information and event management (SEIM) solution for security analysis and compliance. For information about API call quotas, see Quotas for Amazon Verified Permission.

Conclusion

In this post, we demonstrated how you can use multiple Amazon Cognito user pools alongside Amazon Verified Permissions to build a single access layer to APIs. We used Cognito in this example, but you could implement the solution with another third-party IdP instead. As a next step, explore the Cedar playground to test policies that can be used with Verified Permissions, or expand this solution by integrating a third-party IdP.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Akash Kumar

Akash is a Senior Lead Consultant at AWS, based in India. He works with customers for application development, security, and DevOps to modernize and re-architect their workloads to the AWS Cloud. His passion is building innovative solutions and automating infrastructure, enabling customers to focus more on their businesses.

Brett Seib

Brett Seib

Brett is a Senior Solutions Architect, based in Austin, Texas. He is passionate about innovating and using technology to solve business challenges for customers. Brett has several years of experience in the enterprise, Internet of Things (IoT), and data analytics industries, accelerating customer business outcomes.

John Thach

John Thach

John is a Technical Account Manager, based in Houston, Texas. He focuses on enabling customers to implement resilient, secure, and cost-effective solutions by using AWS services. He is passionate about helping customers solve unique challenges through their cloud journeys.

How to use AWS Database Encryption SDK for client-side encryption and perform searches on encrypted attributes in DynamoDB tables

Post Syndicated from Samit Kumbhani original https://aws.amazon.com/blogs/security/how-to-use-aws-database-encryption-sdk-for-client-side-encryption-and-perform-searches-on-encrypted-attributes-in-dynamodb-tables/

Today’s applications collect a lot of data from customers. The data often includes personally identifiable information (PII), that must be protected in compliance with data privacy laws such as the General Data Protection Regulation (GDPR) and the California Consumer Privacy Act (CCPA). Modern business applications require fast and reliable access to customer data, and Amazon DynamoDB is an ideal choice for high-performance applications at scale. While server-side encryption options exist to safeguard customer data, developers can also add client-side encryption to further enhance the security of their customer’s data.

In this blog post, we show you how the AWS Database Encryption SDK (DB-ESDK) – an upgrade to the DynamoDB Encryption Client – provides client-side encryption to protect sensitive data in transit and at rest. At its core, the DB-ESDK is a record encryptor that encrypts, signs, verifies, and decrypts the records in DynamoDB table. You can also use DB-ESDK to search on encrypted records and retrieve data, thereby alleviating the need to download and decrypt your entire dataset locally. In this blog, we demonstrate how to use DB-ESDK to build application code to perform client-side encryption of sensitive data within your application before transmitting and storing it in DynamoDB and then retrieve data by searching on encrypted fields.

Client-side encryption

For protecting data at rest, many AWS services integrate with AWS Key Management Service (AWS KMS). When you use server-side encryption, your plaintext data is encrypted in transit over an HTTPS connection, decrypted at the service endpoint, and then re-encrypted by the service before being stored. Client-side encryption is the act of encrypting your data locally to help ensure its security in transit and at rest. When using client-side encryption, you encrypt the plaintext data from the source (for example, your application) before you transmit the data to an AWS service. This verifies that only the authorized users with the right permission to the encryption key can decrypt the ciphertext data. Because data is encrypted inside an environment that you control, it is not exposed to a third party, including AWS.

While client-side encryption can be used to improve overall security posture, it introduces additional complexity on the application, including managing keys and securely executing cryptographic tasks. Furthermore, client-side encryption often results in reduced portability of the data. After data is encrypted and written to the database, it’s generally not possible to perform additional tasks such as creating index on the data or search directly on the encrypted records without first decrypting it locally. In the next section, you’ll see how you can address these issues by using the AWS Database Encryption SDK (DB-ESDK)—to implement client-side encryption in your DynamoDB workloads and perform searches.

AWS Database Encryption SDK

DB-ESDK can be used to encrypt sensitive attributes such as those containing PII attributes before storing them in your DynamoDB table. This enables your application to help protect sensitive data in transit and at rest, because data cannot be exposed unless decrypted by your application. You can also use DB-ESDK to find information by searching on encrypted attributes while your data remains securely encrypted within the database.

In regards to key management, DB-ESDK gives you direct control over the data by letting you supply your own encryption key. If you’re using AWS KMS, you can use key policies to enforce clear separation between the authorized users who can access specific encrypted data and those who cannot. If your application requires storing multiple tenant’s data in single table, DB-ESDK supports configuring distinct key for each of those tenants to ensure data protection. Follow this link to view how searchable encryption works for multiple tenant databases.

While DB-ESDK provides many features to help you encrypt data in your database, in this blog post, we focus on demonstrating the ability to search on encrypted data.

How the AWS Database Encryption SDK works with DynamoDB

Figure 1: DB-ESDK overview

Figure 1: DB-ESDK overview

As illustrated in Figure 1, there are several steps that you must complete before you can start using the AWS Database Encryption SDK. First, you need to set up your cryptographic material provider library (MPL), which provides you with the lower level abstraction layer for managing cryptographic materials (that is, keyrings and wrapping keys) used for encryption and decryption. The MPL provides integration with AWS KMS as your keyring and allows you to use a symmetric KMS key as your wrapping key. When data needs to be encrypted, DB-ESDK uses envelope encryption and asks the keyring for encryption material. The material consists of a plaintext data key and an encrypted data key, which is encrypted with the wrapping key. DB-ESDK uses the plaintext data key to encrypt the data and stores the ciphertext data key with the encrypted data. This process is reversed for decryption.

The AWS KMS hierarchical keyring goes one step further by introducing a branch key between the wrapping keys and data keys. Because the branch key is cached, it reduces the number of network calls to AWS KMS, providing performance and cost benefits. The hierarchical keyring uses a separate DynamoDB table is referred as the keystore table that must be created in advance. The mapping of wrapping keys to branch keys to data keys is handled automatically by the MPL.

Next, you need to set up the main DynamoDB table for your application. The Java version of DB-ESDK for DynamoDB provides attribute level actions to let you define which attribute should be encrypted. To allow your application to search on encrypted attribute values, you also must configure beacons, which are truncated hashes of plaintext value that create a map between the plaintext and encrypted value and are used to perform the search. These configuration steps are done once for each DynamoDB table. When using beacons, there are tradeoffs between how efficient your queries are and how much information is indirectly revealed about the distribution of your data. You should understand the tradeoff between security and performance before deciding if beacons are right for your use case.

After the MPL and DynamoDB table are set up, you’re ready to use DB-ESDK to perform client-side encryption. To better understand the preceding steps, let’s dive deeper into an example of how this all comes together to insert data and perform searches on a DynamoDB table.

AWS Database Encryption SDK in action

Let’s review the process of setting up DB-ESDK and see it in action. For the purposes of this blog post, let’s build a simple application to add records and performs searches.

The following is a sample plaintext record that’s received by the application:

{
"order_id": "ABC-10001",
“order_time”: “1672531500”,
“email”: "[email protected]",
"first_name": "John",
"last_name": "Doe",
"last4_creditcard": "4567"
"expiry_date": 082026
}

Prerequisite: For client side encryption to work, set up the integrated development environment (IDE) of your choice or set up AWS Cloud9.

Note: To focus on DB-ESDK capabilities, the following instructions omit basic configuration details for DynamoDB and AWS KMS.

Configure DB-ESDK cryptography

As mentioned previously, you must set up the MPL. For this example, you use an AWS KMS hierarchical keyring.

  1. Create KMS key: Create the wrapping key for your keyring. To do this, create a symmetric KMS key using the AWS Management Console or the API.
  2. Create keystore table: Create a DynamoDB table to serve as a keystore to hold the branch keys. The logical keystore name is cryptographically bound to the data stored in the keystore table. The logical keystore name can be the same as your DynamoDB table name, but it doesn’t have to be.
    private static void keyStoreCreateTable(String keyStoreTableName,
                                           String logicalKeyStoreName,
                                           String kmsKeyArn) {
        
        final KeyStore keystore = KeyStore.builder().KeyStoreConfig(
                KeyStoreConfig.builder()
                        .ddbClient(DynamoDbClient.create())
                        .ddbTableName(keyStoreTableName)
                        .logicalKeyStoreName(logicalKeyStoreName)
                        .kmsClient(KmsClient.create())
                        .kmsConfiguration(KMSConfiguration.builder()
                                .kmsKeyArn(kmsKeyArn)
                                .build())
                        .build()).build();
    
        
          keystore.CreateKeyStore(CreateKeyStoreInput.builder().build());
        // It may take a couple minutes for the table to reflect ACTIVE state
    }

  3. Create keystore keys: This operation generates the active branch key and beacon key using the KMS key from step 1 and stores it in the keystore table. The branch and beacon keys will be used by DB-ESDK for encrypting attributes and generating beacons.
    private static String keyStoreCreateKey(String keyStoreTableName,
                                             String logicalKeyStoreName,
                                             String kmsKeyArn) {
       
          final KeyStore keystore = KeyStore.builder().KeyStoreConfig(
                  KeyStoreConfig.builder()
                          .ddbClient(DynamoDbClient.create())
                          .ddbTableName(keyStoreTableName)
                          .logicalKeyStoreName(logicalKeyStoreName)
                          .kmsClient(KmsClient.create())
                          .kmsConfiguration(KMSConfiguration.builder()
                              .kmsKeyArn(kmsKeyArn)
                              .build())
                          .build()).build();
        
          final String branchKeyId = keystore.CreateKey(CreateKeyInput.builder().build()).branchKeyIdentifier();
          return branchKeyId;
      }

At this point, the one-time set up to configure the cryptography material is complete.

Set up a DynamoDB table and beacons

The second step is to set up your DynamoDB table for client-side encryption. In this step, define the attributes that you want to encrypt, define beacons to enable search on encrypted data, and set up the index to query the data. For this example, use the Java client-side encryption library for DynamoDB.

  1. Define DynamoDB table: Define the table schema and the attributes to be encrypted. For this blog post, lets define the schema based on the sample record that was shared previously. To do that, create a DynamoDB table called OrderInfo with order_id as the partition key and order_time as the sort key.

    DB-ESDK provides the following options to define the sensitivity level for each field. Define sensitivity level for each of the attributes based on your use case.

    • ENCRYPT_AND_SIGN: Encrypts and signs the attributes in each record using a unique encryption key. Choose this option for attributes with data you want to encrypt.
    • SIGN_ONLY: Adds a digital signature to verify the authenticity of your data. Choose this option for attributes that you would like to protect from being altered. The partition and sort key should always be set as SIGN_ONLY.
    • DO_NOTHING: Does not encrypt or sign the contents of the field and stores the data as-is. Only choose this option if the field doesn’t contain sensitive data and doesn’t need to be authenticated with the rest of your data. In this example, the partition key and sort key will be defined as “Sign_Only” attributes. All additional table attributes will be defined as “Encrypt and Sign”: email, firstname, lastname, last4creditcard and expirydate.
      private static DynamoDbClient configDDBTable(String ddbTableName, 
                                            IKeyring kmsKeyring, 
                                            List<BeaconVersion> beaconVersions){
      
          // Partition and Sort keys must be SIGN_ONLY
           
          final Map<String, CryptoAction> attributeActionsOnEncrypt = new HashMap<>();
          attributeActionsOnEncrypt.put("order_id", CryptoAction.SIGN_ONLY);
          attributeActionsOnEncrypt.put("order_time", CryptoAction.SIGN_ONLY);
          attributeActionsOnEncrypt.put("email", CryptoAction.ENCRYPT_AND_SIGN);
          attributeActionsOnEncrypt.put("firstname", CryptoAction.ENCRYPT_AND_SIGN);
          attributeActionsOnEncrypt.put("lastname", CryptoAction.ENCRYPT_AND_SIGN);
          attributeActionsOnEncrypt.put("last4creditcard", CryptoAction.ENCRYPT_AND_SIGN);
          attributeActionsOnEncrypt.put("expirydate", CryptoAction.ENCRYPT_AND_SIGN);
      
      
          final Map<String, DynamoDbTableEncryptionConfig> tableConfigs = new HashMap<>();
          final DynamoDbTableEncryptionConfig config = DynamoDbTableEncryptionConfig.builder()
                  .logicalTableName(ddbTableName)
                  .partitionKeyName("order_id")
                  .sortKeyName("order_time")
                  .attributeActionsOnEncrypt(attributeActionsOnEncrypt)
                  .keyring(kmsKeyring)
                  .search(SearchConfig.builder()
                          .writeVersion(1) // MUST be 1
                          .versions(beaconVersions)
                          .build())
                  .build();
          tableConfigs.put(ddbTableName, config);
      
          // Create the DynamoDb Encryption Interceptor
          DynamoDbEncryptionInterceptor encryptionInterceptor = DynamoDbEncryptionInterceptor.builder()
                  .config(DynamoDbTablesEncryptionConfig.builder()
                          .tableEncryptionConfigs(tableConfigs)
                          .build())
                  .build();
      
          // Create a new AWS SDK DynamoDb client using the DynamoDb Encryption Interceptor above
          final DynamoDbClient ddb = DynamoDbClient.builder()
                  .overrideConfiguration(
                          ClientOverrideConfiguration.builder()
                                  .addExecutionInterceptor(encryptionInterceptor)
                                  .build())
                  .build();
          return ddb;
      }

  2. Configure beacons: Beacons allow searches on encrypted fields by creating a mapping between the plaintext value of a field and the encrypted value that’s stored in your database. Beacons are generated by DB-ESDK when the data is being encrypted and written by your application. Beacons are stored in your DynamoDB table along with your encrypted data in fields labelled with the prefix aws_dbe_b_.

    It’s important to note that beacons are designed to be implemented in new, unpopulated tables only. If configured on existing tables, beacons will only map to new records that are written and the older records will not have the values populated. There are two types of beacons – standard and compound. The type of beacon you configure determines the type of queries you are able to perform. You should select the type of beacon based on your queries and access patterns:

    • Standard beacons: This beacon type supports querying a single source field using equality operations such as equals and not-equals. It also allows you to query a virtual (conceptual) field by concatenating one or more source fields.
    • Compound beacons: This beacon type supports querying a combination of encrypted and signed or signed-only fields and performs complex operations such as begins with, contains, between, and so on. For compound beacons, you must first build standard beacons on individual fields. Next, you need to create an encrypted part list using a unique prefix for each of the standard beacons. The prefix should be a short value and helps differentiate the individual fields, simplifying the querying process. And last, you build the compound beacon by concatenating the standard beacons that will be used for searching using a split character. Verify that the split character is unique and doesn’t appear in any of the source fields’ data that the compound beacon is constructed from.

    Along with identifying the right beacon type, each beacon must be configured with additional properties such as a unique name, source field, and beacon length. Continuing the previous example, let’s build beacon configurations for the two scenarios that will be demonstrated in this blog post.

    Scenario 1: Identify orders by exact match on the email address.

    In this scenario, search needs to be conducted on a singular attribute using equality operation.

    • Beacon type: Standard beacon.
    • Beacon name: The name can be the same as the encrypted field name, so let’s set it as email.
    • Beacon length: For this example, set the beacon length to 15. For your own uses cases, see Choosing a beacon length.

    Scenario 2: Identify orders using name (first name and last name) and credit card attributes (last four digits and expiry date).

    In this scenario, multiple attributes are required to conduct a search. To satisfy the use case, one option is to create individual compound beacons on name attributes and credit card attributes. However, the name attributes are considered correlated and, as mentioned in the beacon selection guidance, we should avoid building a compound beacon on such correlated fields. Instead in this scenario we will concatenate the attributes and build a virtual field on the name attributes

    • Beacon type: Compound beacon
    • Beacon Configuration:
      • Define a virtual field on firstname and lastname, and label it fullname.
      • Define standard beacons on each of the individual fields that will be used for searching: fullname, last4creditcard, and expirydate. Follow the guidelines for setting standard beacons as explained in Scenario 1.
      • For compound beacons, create an encrypted part list to concatenate the standard beacons with a unique prefix for each of the standard beacons. The prefix helps separate the individual fields. For this example, use C- for the last four digits of the credit card and E- for the expiry date.
      • Build the compound beacons using their respective encrypted part list and a unique split character. For this example, use ~ as the split character.
    • Beacon length: Set beacon length to 15.
    • Beacon Name: Set the compound beacon name as CardCompound.
    private static List<VirtualField> getVirtualField(){
        
        List<VirtualPart> virtualPartList = new ArrayList<>();
        VirtualPart firstnamePart = VirtualPart.builder()
            .loc("firstname")
            .build();
        VirtualPart lastnamePart = VirtualPart.builder()
            .loc("lastname")
            .build();
    
        virtualPartList.add(firstnamePart);
        virtualPartList.add(lastnamePart);
    
        VirtualField fullnameField = VirtualField.builder()
            .name("FullName")
            .parts(virtualPartList)
            .build();
    
        List<VirtualField> virtualFieldList = new ArrayList<>();
        
        virtualFieldList.add(fullnameField);
        return virtualFieldList;
       }
      
      private static List<StandardBeacon> getStandardBeacon(){
    
        List<StandardBeacon> standardBeaconList = new ArrayList<>();
        StandardBeacon emailBeacon = StandardBeacon
          .builder()
          .name("email")
          .length(15)
          .build();
        StandardBeacon last4creditcardBeacon = StandardBeacon
          .builder()
          .name("last4creditcard")
          .length(15)
          .build();
        StandardBeacon expirydateBeacon = StandardBeacon
          .builder()
          .name("expirydate")
          .length(15)
          .build();  
          
      // Virtual field
        StandardBeacon fullnameBeacon = StandardBeacon
          .builder()
          .name("FullName")
          .length(15)
          .build();  
       
        standardBeaconList.add(emailBeacon);
        standardBeaconList.add(fullnameBeacon);
        standardBeaconList.add(last4creditcardBeacon);
        standardBeaconList.add(expirydateBeacon);
        return standardBeaconList;
      }
    
    // Define compound beacon
      private static List<CompoundBeacon> getCompoundBeacon() {
         
       List<EncryptedPart> encryptedPartList_card = new ArrayList<>(); 
        EncryptedPart last4creditcardEncryptedPart = EncryptedPart
          .builder()
          .name("last4creditcard")
          .prefix("C-")
          .build();
          
        EncryptedPart expirydateEncryptedPart = EncryptedPart
          .builder()
          .name("expirydate")
          .prefix("E-")
          .build();  
          
        encryptedPartList_card.add(last4creditcardEncryptedPart);
        encryptedPartList_card.add(expirydateEncryptedPart);
    
        List<CompoundBeacon> compoundBeaconList = new ArrayList<>();
    
        CompoundBeacon CardCompoundBeacon = CompoundBeacon
          .builder()
          .name("CardCompound")
          .split("~")
          .encrypted(encryptedPartList_card)
          .build();      
    
        compoundBeaconList.add(CardCompoundBeacon);
        return compoundBeaconList;  }
    
    // Build the beacons
    private static List<BeaconVersion> getBeaconVersions(List<StandardBeacon> standardBeaconList, List<CompoundBeacon> compoundBeaconList, KeyStore keyStore, String branchKeyId){
        List<BeaconVersion> beaconVersions = new ArrayList<>();
        beaconVersions.add(
                BeaconVersion.builder()
                        .standardBeacons(standardBeaconList)
                        .compoundBeacons(compoundBeaconList)
                        .version(1) // MUST be 1
                        .keyStore(keyStore)
                        .keySource(BeaconKeySource.builder()
                                .single(SingleKeyStore.builder()
                                        .keyId(branchKeyId)
                                        .cacheTTL(6000)
                                        .build())
                                .build())
                        .build()
        );
        return beaconVersions;
    }

  3. Define index: Following DynamoDB best practices, secondary indexes are often essential to support query patterns. DB-ESDK performs searches on the encrypted fields by doing a look up on the fields with matching beacon values. Therefore, if you need to query an encrypted field, you must create an index on the corresponding beacon fields generated by the DB-ESDK library (attributes with prefix aws_dbe_b_), which will be used by your application for searches.

    For this step, you will manually create a global secondary index (GSI).

    Scenario 1: Create a GSI with aws_dbe_b_email as the partition key and leave the sort key empty. Set the index name as aws_dbe_b_email-index. This will allow searches using the email address attribute.

    Scenario 2: Create a GSI with aws_dbe_b_FullName as the partition key and aws_dbe_b_CardCompound as the sort key. Set the index name as aws_dbe_b_VirtualNameCardCompound-index. This will allow searching based on firstname, lastname, last four digits of the credit card, and the expiry date. At this point the required DynamoDB table setup is complete.

Set up the application to insert and query data

Now that the setup is complete, you can use the DB-ESDK from your application to insert new items into your DynamoDB table. DB-ESDK will automatically fetch the data key from the keyring, perform encryption locally, and then make the put call to DynamoDB. By using beacon fields, the application can perform searches on the encrypted fields.

  1. Keyring initialization: Initialize the AWS KMS hierarchical keyring.
    //Retrieve keystore object required for keyring initialization
    private static KeyStore getKeystore(
        String branchKeyDdbTableName,
        String logicalBranchKeyDdbTableName,
        String branchKeyWrappingKmsKeyArn
      ) {
        KeyStore keyStore = KeyStore
          .builder()
          .KeyStoreConfig(
            KeyStoreConfig
              .builder()
              .kmsClient(KmsClient.create())
              .ddbClient(DynamoDbClient.create())
              .ddbTableName(branchKeyDdbTableName)
              .logicalKeyStoreName(logicalBranchKeyDdbTableName)
              .kmsConfiguration(
                KMSConfiguration
                  .builder()
                  .kmsKeyArn(branchKeyWrappingKmsKeyArn)
                  .build()
              )
              .build()
          )
          .build();
        return keyStore;
      }
    
    //Initialize keyring
    private static IKeyring getKeyRing(String branchKeyId, KeyStore keyStore){
        final MaterialProviders matProv = MaterialProviders.builder()
                .MaterialProvidersConfig(MaterialProvidersConfig.builder().build())
                .build();
        CreateAwsKmsHierarchicalKeyringInput keyringInput = CreateAwsKmsHierarchicalKeyringInput.builder()
                .branchKeyId(branchKeyId)
                .keyStore(keyStore)
                .ttlSeconds(60)
                .build();
        final IKeyring kmsKeyring = matProv.CreateAwsKmsHierarchicalKeyring(keyringInput);
      
        return kmsKeyring;
    }

  2. Insert source data: For illustration purpose, lets define a method to load sample data into the OrderInfo table. By using DB-ESDK, the application will encrypt data attributes as defined in the DynamoDB table configuration steps.
    // Insert Order Data
      private static void insertOrder(HashMap<String, AttributeValue> order, DynamoDbClient ddb, String ddbTableName) {
    
        final PutItemRequest putRequest = PutItemRequest.builder()
            .tableName(ddbTableName)
            .item(order)
            .build();
    
        final PutItemResponse putResponse = ddb.putItem(putRequest);
        assert 200 == putResponse.sdkHttpResponse().statusCode();
      }
      
        private static HashMap<String, AttributeValue> getOrder(
        String orderId,
        String orderTime,
        String firstName,
        String lastName,
        String email,
        String last4creditcard,
        String expirydate
      ) 
      {
        final HashMap<String, AttributeValue> order = new HashMap<>();
        order.put("order_id", AttributeValue.builder().s(orderId).build());
        order.put("order_time", AttributeValue.builder().s(orderTime).build());
        order.put("firstname", AttributeValue.builder().s(firstName).build());
        order.put("lastname", AttributeValue.builder().s(lastName).build());
        order.put("email", AttributeValue.builder().s(email).build());
        order.put("last4creditcard", AttributeValue.builder().s(last4creditcard).build());
        order.put("expirydate", AttributeValue.builder().s(expirydate).build());
    
        return order;
      }

  3. Query Data: Define a method to query data using plaintext values

    Scenario 1: Identify orders associated with email address [email protected]. This query should return Order ID ABC-1001.

    private static void runQueryEmail(DynamoDbClient ddb, String ddbTableName) {
        Map<String, String> expressionAttributesNames = new HashMap<>();
        expressionAttributesNames.put("#e", "email");
    
        Map<String, AttributeValue> expressionAttributeValues = new HashMap<>();
        expressionAttributeValues.put(
          ":e",
          AttributeValue.builder().s("[email protected]").build()
        );
    
        QueryRequest queryRequest = QueryRequest
          .builder()
          .tableName(ddbTableName)
          .indexName("aws_dbe_b_email-index")
          .keyConditionExpression("#e = :e")
          .expressionAttributeNames(expressionAttributesNames)
          .expressionAttributeValues(expressionAttributeValues)
          .build();
    
        final QueryResponse queryResponse = ddb.query(queryRequest);
        assert 200 == queryResponse.sdkHttpResponse().statusCode();
    
        List<Map<String, AttributeValue>> items = queryResponse.items();
    
        for (Map<String, AttributeValue> returnedItem : items) {
          System.out.println(returnedItem.get("order_id").s());
        }
      }

    Scenario 2: Identify orders that were placed by John Doe using a specific credit card with the last four digits of 4567 and expiry date of 082026. This query should return Order ID ABC-1003 and ABC-1004.

    private static void runQueryNameCard(DynamoDbClient ddb, String ddbTableName) {
        Map<String, String> expressionAttributesNames = new HashMap<>();
        expressionAttributesNames.put("#PKName", "FullName");
        expressionAttributesNames.put("#SKName", "CardCompound");
    
    
       Map<String, AttributeValue> expressionAttributeValues = new HashMap<>();
        expressionAttributeValues.put(
          ":PKValue",
          AttributeValue.builder().s("JohnDoe").build()
          );
        expressionAttributeValues.put(
          ":SKValue",
          AttributeValue.builder().s("C-4567~E-082026").build()
          ); 
        
        QueryRequest queryRequest = QueryRequest
          .builder()
          .tableName(ddbTableName)
          .indexName("aws_dbe_b_VirtualNameCardCompound-index")
          .keyConditionExpression("#PKName = :PKValue and #SKName = :SKValue")
          .expressionAttributeNames(expressionAttributesNames)
          .expressionAttributeValues(expressionAttributeValues)
          .build();
        final QueryResponse queryResponse = ddb.query(queryRequest);
    
        // Validate query was returned successfully
        assert 200 == queryResponse.sdkHttpResponse().statusCode();
    
        List<Map<String, AttributeValue>> items = queryResponse.items();
    
        for (Map<String, AttributeValue> returnedItem : items) {
          System.out.println(returnedItem.get("order_id").s());
        }
      }

    Note: Compound beacons support complex string operation such as begins_with. In Scenario 2, if you had only the name attributes and last four digits of the credit card, you could still use the compound beacon for querying. You can set the values as shown below to query the beacon using the same code:

    PKValue = “JohnDoe”
    SKValue = "C-4567”
    keyConditionExpression = "#PKName = :PKValue and begins_with(#SKName, :SKValue)"

Now that you have the building blocks, let’s bring this all together and run the following steps to set up the application. For this example, a few of the input parameters have been hard coded. In your application code, replace <KMS key ARN> and <branch-key-id derived from keystore table> from Step 1 and Step 3 mentioned in the Configure DB-ESDK cryptography sections.

//Hard coded values for illustration
String keyStoreTableName = "tblKeyStore";
String logicalKeyStoreName = "lglKeyStore";
String kmsKeyArn = "<KMS key ARN>";
String ddbTableName = "OrderInfo";
String branchKeyId = "<branch-key-id derived from keystore table>";
String branchKeyWrappingKmsKeyArn = "<KMS key ARN>";
String branchKeyDdbTableName = keyStoreTableName;


//run only once to setup keystore 
keyStoreCreateTable(keyStoreTableName, logicalKeyStoreName, kmsKeyArn);

//run only once to create branch and beacon key
keyStoreCreateKey(keyStoreTableName, logicalKeyStoreName, kmsKeyArn);

//run configuration per DynamoDb table 
List<VirtualField> virtualField = getVirtualField();
List<StandardBeacon> beacon = getStandardBeacon ();
List<CompoundBeacon> compoundBeacon = getCompoundBeacon();
KeyStore keyStore = getKeystore(branchKeyDdbTableName, logicalKeyStoreName, branchKeyWrappingKmsKeyArn);
List<BeaconVersion> beaconVersions = getBeaconVersions(beacon, compoundBeacon, keyStore, branchKeyId);
IKeyring keyRing = getKeyRing(branchKeyId, keyStore);
DynamoDbClient ddb = configDDBTable(ddbTableName, keyRing, beaconVersions);

//insert sample records
    HashMap<String, AttributeValue> order1 = getOrder("ABC-1001", "1672531200", "Mary", "Major", "[email protected]", "1234", "012001");
    HashMap<String, AttributeValue> order2 = getOrder("ABC-1002", "1672531400", "John", "Doe", "[email protected]", "1111", "122023");
    HashMap<String, AttributeValue> order3 = getOrder("ABC-1003", "1672531500", "John", "Doe", "[email protected]","4567", "082026");
    HashMap<String, AttributeValue> order4 = getOrder("ABC-1004", "1672531600", "John", "Doe", "[email protected]","4567", "082026");

   insertOrder(order1, ddb, ddbTableName);
   insertOrder(order2, ddb, ddbTableName);
   insertOrder(order3, ddb, ddbTableName);
   insertOrder(order4, ddb, ddbTableName);

//Query OrderInfo table
runQueryEmail(ddb, ddbTableName); //returns orderid ABC-1001
runQueryNameCard(ddb, ddbTableName); // returns orderid ABC-1003, ABC-1004

Conclusion

You’ve just seen how to build an application that encrypts sensitive data on client side, stores it in a DynamoDB table and performs queries on the encrypted data transparently to the application code without decrypting the entire data set. This allows your applications to realize the full potential of the encrypted data while adhering to security and compliance requirements. The code snippet used in this blog is available for reference on GitHub. You can further read the documentation of the AWS Database Encryption SDK and reference the source code at this repository. We encourage you to explore other examples of searching on encrypted fields referenced in this GitHub repository.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Samit Kumbhani

Samit Kumbhani

Samit is an AWS Sr. Solutions Architect in the New York City area. He has 18 years of experience building applications and focuses on Analytics, Business Intelligence, and Databases. He enjoys working with customers to understand and solve their challenges by creating innovative solutions using AWS services. Samit enjoys playing cricket, traveling, and biking.

Author

Nir Ozeri

Nir is a Solutions Architect Manager with Amazon Web Services, based out of New York City. Nir specializes in application modernization, application delivery, and mobile architecture.

Yuri Duchovny

Yuri Duchovny

Yuri is a New York–based Principal Solutions Architect specializing in cloud security, identity, and compliance. He supports cloud transformations at large enterprises, helping them make optimal technology and organizational decisions. Prior to his AWS role, Yuri’s areas of focus included application and networking security, DoS, and fraud protection. Outside of work, he enjoys skiing, sailing, and traveling the world.

OT/IT convergence security maturity model

Post Syndicated from James Hobbs original https://aws.amazon.com/blogs/security/ot-it-convergence-security-maturity-model/

For decades, we’ve watched energy companies attempt to bring off-the-shelf information technology (IT) systems into operations technology (OT) environments. These attempts have had varying degrees of success. While converging OT and IT brings new efficiencies, it also brings new risks. There are many moving parts to convergence, and there are several questions that you must answer, such as, “Are systems, processes, and organizations at the same point in their convergence journey?” and “Are risks still being managed well?”

To help you answer these questions, this post provides an aid in the form of a maturity model focused on the security of OT/IT convergence.

OT environments consist of industrial systems that measure, automate, and control physical machines. Because of this, OT risk management must consider potential risks to environment, health, and safety. Adding common IT components can add to these risks. For example, OT networks were typically highly segmented to reduce exposure to external untrusted networks while IT has a seemingly ever-growing network surface. Because of this growing surface, IT networks have built-in resiliency against cyber threats, though they weren’t originally designed for the operational requirements found in OT. However, you can use the strengths of Amazon Web Services (AWS) to help meet regulatory requirements and manage risks in both OT and IT.

The merging of OT and IT has begun at most companies and includes the merging of systems, organizations, and policies. These components are often at different points along their journey, making it necessary to identify each one and where it is in the process to determine where additional attention is needed. Another purpose of the OT/IT security convergence model is to help identify those maturity points.

Patterns in this model often reference specific aspects of how much involvement OT teams have in overall IT and cloud strategies. It’s important to understand that OT is no longer an air-gapped system that is hidden away from cyber risks, and so it now shares many of the same risks as IT. This understanding enables and improves your preparedness for a safe and secure industrial digital transformation using AWS to accelerate your convergence journey.

Getting started with secure OT/IT convergence

The first step in a secure OT/IT convergence is to ask questions. The answers to these questions lead to establishing maturity patterns. For example, the answer might indicate a quick win for convergence, or it might demonstrate a more optimized maturity level. In this section, we review the questions you should ask about your organization:

  1. When was the last time your organization conducted an OT/IT cybersecurity risk assessment using a common framework (such as ISA/IEC 62443) and used it to inform system design?

    When taking advantage of IT technologies in OT environments, it’s important to conduct a cybersecurity risk assessment to fully understand and proactively manage risks. For risk assessments, companies with maturing OT/IT convergence display common patterns. Some patterns to be aware of are:

    • The frequency of risk assessments is driven by risk measures and data
    • IT technologies are successfully being adopted into OT environments
    • Specific cybersecurity risk assessments are conducted in OT
    • Risk assessments are conducted at the start of Industrial Internet of Things (IIoT) projects
    • Risk assessments inform system designs
    • Proactively managing risks, gaps, and vulnerabilities between OT and IT
    • Up-to-date threat modeling capabilities for both OT and IT

    For more information, see:

  2. What is the extent and maturity of IIoT enabled digital transformation in your organization?

    There are several good indicators to determine the maturity of IIoT’s effect on OT/IT convergence in an organization. For example, the number of IIoT implementations with well-defined security controls. Also, the number of IIoT digital use cases developed and realized. Additionally, some maturing IIoT convergence practices are:

    • Simplification and standardization of IIoT security controls
    • Scaling digital use cases across the shop floor
    • IIoT being consumed collaboratively or within organizational silos
    • Integrated IIoT enterprise applications
    • Identifying connections to external networks and how they are routed
    • IoT use cases identified and implemented across multiple industrial sites

    For more information, see:


  3. Does your organization maintain an inventory of connected assets and use it to manage risk effectively?

    A critical aspect of a good security program is having visibility into your entire OT and IIoT system and knowing which systems don’t support open networks and modern security controls. Since you can’t protect what you can’t see, your organization must have comprehensive asset visibility. Highly capable asset management processes typically demonstrate the following considerations:

    • Visibility across your entire OT and IIoT system
    • Identifies systems not supporting open networks and modern security controls
    • Vulnerabilities and threats readily map to assets and asset owners
    • Asset visibility is used to improve cybersecurity posture
    • An up-to-date and clear understanding of the OT/IIoT network architecture
    • Defined locations for OT data including asset and configuration data
    • Automated asset inventory with modern discovery processes in OT
    • Asset inventory collections that are non-disruptive and do not introduce new vulnerabilities to OT

    For more information, see:


  4. Does your organization have an incident response plan for converged OT and IT environments?

    Incident response planning is essential for critical infrastructure organizations to minimize the impacts of cyber events. Some considerations are:

    • An incident response plan that aims to minimize the effects of a cyber event
    • The effect of incidents on an organization’s operations, reputation, and assets
    • Developed and tested incident response runbooks
    • A plan identifying potential risks and vulnerabilities
    • A plan prioritizing and allocating response personnel
    • Established clear roles and responsibilities
    • Documented communication procedures, backup, and recovery
    • Defined incident escalation procedures
    • Frequency of response plan testing and cyber drills
    • Incident response collaboration between OT and IT authorities
    • Relying on individuals versus team processes for incident response
    • Measuring incident response OT/IT coordination hesitation during drills
    • An authoritative decision maker across OT and IT for seamless incident response leadership

    For more information, see:


  5. With reference to corporate governance, are OT and IT using separate policies and controls to manage cybersecurity risks or are they using the same policy?

    The ongoing maturity and adoption of cloud within IT and now within OT creates a more common environment. A comprehensive enterprise and OT security policy will encompass risks across the entirety of the business. This allows for OT risks such as safety to be recognized and addressed within IT. Conversely, this allows for IT risks such as bots and ransomware to be addressed within OT. While policies might converge, mitigation strategies will still differ in many cases. Some considerations are:

    • OT and IT maintaining separate risk policies.
    • Assuming air-gapped OT systems.
    • The degree of isolation for process control and safety networks.
    • Interconnectedness of OT and IT systems and networks.
    • Security risks that were applicable to either IT or OT might now apply to both.
    • OT comprehension of risks related to lateral movement.
    • Singular security control policy that governs both OT and IT.
    • Different mitigation strategies as appropriate for OT and for IT. For example, the speed of patching is often different between OT and IT by design.
    • Different risk measures maintained between OT and IT.
    • A common view of risk to the business.
    • The use of holistic approaches to manage OT and IT risk.

    For more information, see:


  6. Is there a central cloud center of excellence (CCoE) with equivalent representation from OT and IT?

    Consolidating resources into centers of excellence has proven an effective way to bring focus to new or transforming enterprises. Many companies have created CCoEs around security within the past two decades to consolidate experts from around the company. Such focused areas are a central point of technical authority and accelerates decision making. Some considerations are:

    • Consolidating resources into centers of excellence.
    • Security experts consolidated from around the company into a singular organization.
    • Defining security focus areas based on risk priorities.
    • Having a central point of security authority.
    • OT and IT teams operating uniformly.
    • Well understood and applied incident response decision rights in OT.

    For more information, see:


  7. Is there a clear definition of the business value of converging OT and IT?

    Security projects face extra scrutiny from multiple parties ranging from shareholders to regulators. Because of this, each project must be tied to business and operational outcomes. The value of securing converged OT and IT technologies is realized by maintaining and improving operations and resilience. Some considerations are:

    • Security projects are tied to appropriate outcomes
    • The same measures are used to track security program benefits across OT and IT.
    • OT and IT security budgets merged.
    • The CISO has visibility to OT security risk data.
    • OT personnel are invited to cloud strategy meetings.
    • OT and IT security reporting is through a singular leader such as a CISO.
    • Engagement of OT personnel in IT security meetings.

    For more information, see:


  8. Does your organization have security monitoring across the full threat surface?

    With the increasing convergence of OT and IT, the digital threat surface has expanded and organizations must deploy security audit and monitoring mechanisms across OT, IIoT, edge, and cloud environments and collect security logs for analysis using security information and event management (SIEM) tools within a security operations center (SOC). Without full visibility of traffic entering and exiting OT networks, a quickly spreading event between OT and IT might go undetected. Some considerations are:

    • Awareness of the expanding digital attack surface.
    • Security audit and monitoring mechanisms across OT, IIoT, edge, and cloud environments.
    • Security logs collected for analysis using SIEM tools within a SOC.
    • Full visibility and control of traffic entering and exiting OT networks.
    • Malicious threat actor capabilities for destructive consequences to physical cyber systems.
    • The downstream impacts resulting in OT networks being shut down due to safety concerns.
    • The ability to safely operate and monitor OT networks during a security event.
    • Benefits of a unified SOC.
    • Coordinated threat detection and immediate sharing of indicators enabled.
    • Access to teams that can map potential attack paths and origins.

    For more information, see:


  9. Does your IT team fully comprehend the differences in priority between OT and IT with regard to availability, integrity, and confidentiality?

    Downtime equals lost revenue. While this is true in IT as well, it is less direct than it is in OT and can often be overcome with a variety of redundancy strategies. While the OT formula for data and systems is availability, integrity, then confidentiality, it also focuses on safety and reliability. To develop a holistic picture of corporate security risks, you must understand that systems in OT have been and will continue to be built with availability as the key component. Some considerations are:

    • Availability is vital in OT. Systems must run in order to produce and manufacture product. Downtime equals lost revenue.
    • IT redundancy strategies might not directly translate to OT.
    • OT owners previously relied on air-gapped systems or layers of defenses to achieve confidentiality.
    • Must have a holistic picture of all corporate security risks.
    • Security defenses are often designed to wrap around OT zones while restricting the conduits between them.
    • OT and IT risks are managed collectively.
    • Implement common security controls between OT and IT.

    For more information, see:


  10. Are your OT support teams engaged with cloud strategy?

    Given the historical nature of the separation of IT and OT, organizations might still operate in silos. An indication of converging maturity is how well those teams are working across divisions or have even removed silos altogether. OT systems are part of larger safety and risk management programs within industrial systems from which many IT systems have typically remained separated. As the National Institute of Standards and Technology states, “To properly address security in an industrial control system (ICS), it is essential for a cross-functional cybersecurity team to share their varied domain knowledge and experience to evaluate and mitigate risk to the ICS.” [NIST 800-82r2, Pg. 3]. Some considerations are:

    • OT experts should be directly involved in security and cloud strategy.
    • OT systems are part of larger safety and risk management programs.
    • Make sure that communications between OT and IT aren’t limited or strained.
    • OT and IT personnel should interact regularly.
    • OT personnel should not only be informed of cloud strategies, but should be active participants.

    For more information, see:


  11. How much of your cloud security across OT and IT is managed manually and how much is automated?

    Security automation means addressing threats automatically by providing predefined response and remediation actions based on compliance standards or best practices. Automation can resolve common security findings to improve your posture within AWS. It also allows you to quickly respond to threat events. Some considerations are:

    • Cyber responses are predefined and are real-time.
    • Playbooks exist and include OT scenarios.
    • Automated remediations are routine practice.
    • Foundational security is automated.
    • Audit trails are enabled with notifications for automated actions.
    • OT events are aggregated, prioritized, and consumed into orchestration tools.
    • Cloud security postures for OT and IT are understood and documented.

    For more information, see:


  12. To what degree are your OT and IT networks segmented?

    Network segmentation has been well established as a foundational security practice. NIST SP800-82r3 pg.72 states, “Implementing network segmentation utilizing levels, tiers, or zones allows organizations to control access to sensitive information and components while also considering operational performance and safety.”

    Minimizing network access to OT systems reduces the available threat surface. Typically, firewalls are used as control points between different segments. Several models exist showing separation of OT and IT networks and maintaining boundary zones between the two. As stated in section 5.2.3.1 “A good practice for network architectures is to characterize, segment, and isolate IT and OT devices.” (NIST SP800-82r3).

    AWS provides multiple ways to segment and firewall network boundaries depending upon requirements and customer needs. Some considerations are:

    • Existence of a perimeter network between OT and IT.
    • Level of audit and inspection of perimeter network traffic.
    • Amount of direct connectivity between OT and IT.
    • Segmentation is regularly tested for threat surface vulnerabilities.
    • Use of cloud-native tools to manage networks.
    • Identification and use of high-risk ports.
    • OT and IT personnel are collaborative network boundary decision makers.
    • Network boundary changes include OT risk management methodologies.
    • Defense in depth measures are evident.
    • Network flow log data analysis.

    For more information, see:

The following table describes typical patterns seen at each maturity level.

Phase 1: Quick wins Phase 2: Foundational Phase 3: Efficient Phase 4: Optimized
1 When was the last time your organization conducted an OT/IT cybersecurity risk assessment using a common framework (such as ISA/IEC 62443) and used it to inform system design? A basic risk assessment performed to identify risks, gaps, and vulnerabilities Organization has manual threat modeling capabilities and maintains an up-to-date threat model Organization has automated threat modeling capabilities using the latest tools Organization maintains threat modeling automation as code and an agile ability to use the latest tools
2 What is the extent and maturity of IIoT enabled digital transformation in your organization? Organization is actively introducing IIoT on proof-of-value projects Organization is moving from proof-of-value projects to production pilots Organization is actively identifying and prioritizing business opportunities and use cases and using the lessons learned from pilot sites to reduce the time-to-value at other sites Organization is scaling the use of IIoT across multiple use cases, sites, and assets and can rapidly iterate new IIoT to meet changing business needs
3 Does your organization maintain an inventory of connected assets and use it to manage risk effectively? Manual tracking of connected assets with no automated tools for new asset discovery Introduction of asset discovery tools to discover and create an inventory of all connected assets Automated tools for asset discovery, inventory management, and frequent reporting Near real time asset discovery and consolidated inventory in a configuration management database (CMDB)
4 Does your organization have an incident response plan for converged OT and IT environments? Organization has separate incident response plans for OT and IT environments Organization has an ICS-specific incident response plan to account for the complexities and operational necessities of responding in operational environments Cyber operators are trained to ensure process safety and system reliability when responding to security events in converged OT/IT environments Organization has incident response plans and playbooks for converged OT/IT environments
5 With reference to corporate governance, are OT and IT using separate policies and controls to manage cybersecurity risks or are they using the same policy? Organization has separate risk policies for OT and IT environments Organization has some combined policies across OT and IT but might not account for all OT risks Organization accounts for OT risks such as health and safety in a central cyber risk register Organization has codified central risk management policy accounting for both OT and IT risks
6 Is there a central cloud center of excellence (CCoE) with equivalent representation from OT and IT? Cloud CoE exists with as-needed engagement from OT on special projects Some representation from OT in cloud CoE Increasing representation from OT in cloud CoE Cloud CoE exists with good representation from OT and IT
7 Is there a clear definition of the business value of converging OT and IT? No clear definition of business value from convergence projects Organization working towards defining key performance indicators (KPIs) for convergence projects Organization has identified KPIs and created a baseline of their current as-is state Organization is actively measuring KPIs on convergence projects
8 Does your organization have security monitoring across the full threat surface? Stand-alone monitoring systems in OT and IT with no integration between systems Limited integration between OT and IT monitoring systems and may have separate SOCs Increasing integration between OT and IT systems with some holistic SOC activities Convergence of OT and IT security monitoring in a unified and global SOC
9 Does your IT team fully comprehend the differences in priority between IT and OT with regard to availability, integrity, and confidentiality? IT teams lack an understanding of the priorities in OT as they relate to safety and availability IT teams have a high level understanding of the differences between OT and IT risks and OT teams understand cyber threat models IT teams being trained on the priorities and differences of OT systems and include them in cyber risk measures IT fully understands the differences and increased risk from OT/IT convergence and members work on cross-functional teams as interchangeable experts
10 Are your OT support teams engaged with cloud strategy? Separate OT and IT teams with limited collaboration on projects Limited OT team engagement in cloud strategy Increasing OT team engagement in cloud security OT teams actively engaged with cloud strategy
11 How much of your cloud security across OT and IT is managed manually and how much is automated? Processes are manual and use non-enterprise grade tools Automation exists in pockets within OT Security decisions are increasingly automated and iterated upon with guardrails in place Manual steps are minimized and security decisions are automated as code
12 To what degree are your OT and IT networks segmented? Limited segmentation between OT and IT networks Introduction of an industrial perimeter network between OT and IT networks Industrial perimeter network exists with some OT network segmentation Industrial perimeter network between OT and IT networks with micro-network segmentation within OT and IT networks

Conclusion

In this post, you learned how you can use this OT/IT convergence security maturity model to help identify areas for improvement. There were 12 questions and patterns that are examples you can build upon. This model isn’t the end, but a guide for getting started. Successful implementation of OT/IT convergence for industrial digital transformation requires ongoing strategic security management because it’s not just about technology integration. The risks of cyber events that OT/IT convergence exposes must be addressed. Organizations fall into various levels of maturity. These are quick wins, foundational, efficient, and optimized. AWS tools, guidance, and professional services can help accelerate your journey to both technical and organizational maturity.

Additional reading

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

James Hobbs

James Hobbs

James is a Security Principal for AWS Energy & Utilities Professional Services. He has over 30 years of IT experience, including 20 years leading cybersecurity and incident response teams for the world’s largest Energy companies. He spent years focused on OT security and controls. He guides internal security practices and advises Energy customers on OT and IT cybersecurity practices.

Ryan Dsouza

Ryan Dsouza

Ryan is a Principal IoT Security Solutions Architect at AWS. Based in NYC, Ryan helps customers design, develop, and operate more secure, scalable, and innovative IIoT solutions using the breadth and depth of AWS capabilities to deliver measurable business outcomes. He is passionate about bringing security to all connected devices and being a champion of building a better, safer, and more resilient world for everyone.

Power neural search with AI/ML connectors in Amazon OpenSearch Service

Post Syndicated from Aruna Govindaraju original https://aws.amazon.com/blogs/big-data/power-neural-search-with-ai-ml-connectors-in-amazon-opensearch-service/

With the launch of the neural search feature for Amazon OpenSearch Service in OpenSearch 2.9, it’s now effortless to integrate with AI/ML models to power semantic search and other use cases. OpenSearch Service has supported both lexical and vector search since the introduction of its k-nearest neighbor (k-NN) feature in 2020; however, configuring semantic search required building a framework to integrate machine learning (ML) models to ingest and search. The neural search feature facilitates text-to-vector transformation during ingestion and search. When you use a neural query during search, the query is translated into a vector embedding and k-NN is used to return the nearest vector embeddings from the corpus.

To use neural search, you must set up an ML model. We recommend configuring AI/ML connectors to AWS AI and ML services (such as Amazon SageMaker or Amazon Bedrock) or third-party alternatives. Starting with version 2.9 on OpenSearch Service, AI/ML connectors integrate with neural search to simplify and operationalize the translation of your data corpus and queries to vector embeddings, thereby removing much of the complexity of vector hydration and search.

In this post, we demonstrate how to configure AI/ML connectors to external models through the OpenSearch Service console.

Solution Overview

Specifically, this post walks you through connecting to a model in SageMaker. Then we guide you through using the connector to configure semantic search on OpenSearch Service as an example of a use case that is supported through connection to an ML model. Amazon Bedrock and SageMaker integrations are currently supported on the OpenSearch Service console UI, and the list of UI-supported first- and third-party integrations will continue to grow.

For any models not supported through the UI, you can instead set them up using the available APIs and the ML blueprints. For more information, refer to Introduction to OpenSearch Models. You can find blueprints for each connector in the ML Commons GitHub repository.

Prerequisites

Before connecting the model via the OpenSearch Service console, create an OpenSearch Service domain. Map an AWS Identity and Access Management (IAM) role by the name LambdaInvokeOpenSearchMLCommonsRole as the backend role on the ml_full_access role using the Security plugin on OpenSearch Dashboards, as shown in the following video. The OpenSearch Service integrations workflow is pre-filled to use the LambdaInvokeOpenSearchMLCommonsRole IAM role by default to create the connector between the OpenSearch Service domain and the model deployed on SageMaker. If you use a custom IAM role on the OpenSearch Service console integrations, make sure the custom role is mapped as the backend role with ml_full_access permissions prior to deploying the template.

Deploy the model using AWS CloudFormation

The following video demonstrates the steps to use the OpenSearch Service console to deploy a model within minutes on Amazon SageMaker and generate the model ID via the AI connectors. The first step is to choose Integrations in the navigation pane on the OpenSearch Service AWS console, which routes to a list of available integrations. The integration is set up through a UI, which will prompt you for the necessary inputs.

To set up the integration, you only need to provide the OpenSearch Service domain endpoint and provide a model name to uniquely identify the model connection. By default, the template deploys the Hugging Face sentence-transformers model, djl://ai.djl.huggingface.pytorch/sentence-transformers/all-MiniLM-L6-v2.

When you choose Create Stack, you are routed to the AWS CloudFormation console. The CloudFormation template deploys the architecture detailed in the following diagram.

The CloudFormation stack creates an AWS Lambda application that deploys a model from Amazon Simple Storage Service (Amazon S3), creates the connector, and generates the model ID in the output. You can then use this model ID to create a semantic index.

If the default all-MiniLM-L6-v2 model doesn’t serve your purpose, you can deploy any text embedding model of your choice on the chosen model host (SageMaker or Amazon Bedrock) by providing your model artifacts as an accessible S3 object. Alternatively, you can select one of the following pre-trained language models and deploy it to SageMaker. For instructions to set up your endpoint and models, refer to Available Amazon SageMaker Images.

SageMaker is a fully managed service that brings together a broad set of tools to enable high-performance, low-cost ML for any use case, delivering key benefits such as model monitoring, serverless hosting, and workflow automation for continuous training and deployment. SageMaker allows you to host and manage the lifecycle of text embedding models, and use them to power semantic search queries in OpenSearch Service. When connected, SageMaker hosts your models and OpenSearch Service is used to query based on inference results from SageMaker.

View the deployed model through OpenSearch Dashboards

To verify the CloudFormation template successfully deployed the model on the OpenSearch Service domain and get the model ID, you can use the ML Commons REST GET API through OpenSearch Dashboards Dev Tools.

The GET _plugins REST API now provides additional APIs to also view the model status. The following command allows you to see the status of a remote model:

GET _plugins/_ml/models/<modelid>

As shown in the following screenshot, a DEPLOYED status in the response indicates the model is successfully deployed on the OpenSearch Service cluster.

Alternatively, you can view the model deployed on your OpenSearch Service domain using the Machine Learning page of OpenSearch Dashboards.

This page lists the model information and the statuses of all the models deployed.

Create the neural pipeline using the model ID

When the status of the model shows as either DEPLOYED in Dev Tools or green and Responding in OpenSearch Dashboards, you can use the model ID to build your neural ingest pipeline. The following ingest pipeline is run in your domain’s OpenSearch Dashboards Dev Tools. Make sure you replace the model ID with the unique ID generated for the model deployed on your domain.

PUT _ingest/pipeline/neural-pipeline
{
  "description": "Semantic Search for retail product catalog ",
  "processors" : [
    {
      "text_embedding": {
        "model_id": "sfG4zosBIsICJFsINo3X",
        "field_map": {
           "description": "desc_v",
           "name": "name_v"
        }
      }
    }
  ]
}

Create the semantic search index using the neural pipeline as the default pipeline

You can now define your index mapping with the default pipeline configured to use the new neural pipeline you created in the previous step. Ensure the vector fields are declared as knn_vector and the dimensions are appropriate to the model that is deployed on SageMaker. If you have retained the default configuration to deploy the all-MiniLM-L6-v2 model on SageMaker, keep the following settings as is and run the command in Dev Tools.

PUT semantic_demostore
{
  "settings": {
    "index.knn": true,  
    "default_pipeline": "neural-pipeline",
    "number_of_shards": 1,
    "number_of_replicas": 1
  },
  "mappings": {
    "properties": {
      "desc_v": {
        "type": "knn_vector",
        "dimension": 384,
        "method": {
          "name": "hnsw",
          "engine": "nmslib",
          "space_type": "cosinesimil"
        }
      },
      "name_v": {
        "type": "knn_vector",
        "dimension": 384,
        "method": {
          "name": "hnsw",
          "engine": "nmslib",
          "space_type": "cosinesimil"
        }
      },
      "description": {
        "type": "text" 
      },
      "name": {
        "type": "text" 
      } 
    }
  }
}

Ingest sample documents to generate vectors

For this demo, you can ingest the sample retail demostore product catalog to the new semantic_demostore index. Replace the user name, password, and domain endpoint with your domain information and ingest raw data into OpenSearch Service:

curl -XPOST -u 'username:password' 'https://domain-end-point/_bulk' --data-binary @semantic_demostore.json -H 'Content-Type: application/json'

Validate the new semantic_demostore index

Now that you have ingested your dataset to the OpenSearch Service domain, validate if the required vectors are generated using a simple search to fetch all fields. Validate if the fields defined as knn_vectors have the required vectors.

Compare lexical search and semantic search powered by neural search using the Compare Search Results tool

The Compare Search Results tool on OpenSearch Dashboards is available for production workloads. You can navigate to the Compare search results page and compare query results between lexical search and neural search configured to use the model ID generated earlier.

Clean up

You can delete the resources you created following the instructions in this post by deleting the CloudFormation stack. This will delete the Lambda resources and the S3 bucket that contain the model that was deployed to SageMaker. Complete the following steps:

  1. On the AWS CloudFormation console, navigate to your stack details page.
  2. Choose Delete.

  1. Choose Delete to confirm.

You can monitor the stack deletion progress on the AWS CloudFormation console.

Note that, deleting the CloudFormation stack doesn’t delete the model deployed on the SageMaker domain and the AI/ML connector created. This is because these models and the connector can be associated with multiple indexes within the domain. To specifically delete a model and its associated connector, use the model APIs as shown in the following screenshots.

First, undeploy the model from the OpenSearch Service domain memory:

POST /_plugins/_ml/models/<model_id>/_undeploy

Then you can delete the model from the model index:

DELETE /_plugins/_ml/models/<model_id>

Lastly, delete the connector from the connector index:

DELETE /_plugins/_ml/connectors/<connector_id>

Conclusion

In this post, you learned how to deploy a model in SageMaker, create the AI/ML connector using the OpenSearch Service console, and build the neural search index. The ability to configure AI/ML connectors in OpenSearch Service simplifies the vector hydration process by making the integrations to external models native. You can create a neural search index in minutes using the neural ingestion pipeline and the neural search that use the model ID to generate the vector embedding on the fly during ingest and search.

To learn more about these AI/ML connectors, refer to Amazon OpenSearch Service AI connectors for AWS services, AWS CloudFormation template integrations for semantic search, and Creating connectors for third-party ML platforms.


About the Authors

Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience.

Dagney Braun is a Principal Product Manager at AWS focused on OpenSearch.

Strengthen the DevOps pipeline and protect data with AWS Secrets Manager, AWS KMS, and AWS Certificate Manager

Post Syndicated from Magesh Dhanasekaran original https://aws.amazon.com/blogs/security/strengthen-the-devops-pipeline-and-protect-data-with-aws-secrets-manager-aws-kms-and-aws-certificate-manager/

In this blog post, we delve into using Amazon Web Services (AWS) data protection services such as Amazon Secrets Manager, AWS Key Management Service (AWS KMS), and AWS Certificate Manager (ACM) to help fortify both the security of the pipeline and security in the pipeline. We explore how these services contribute to the overall security of the DevOps pipeline infrastructure while enabling seamless integration of data protection measures. We also provide practical insights by demonstrating the implementation of these services within a DevOps pipeline for a three-tier WordPress web application deployed using Amazon Elastic Kubernetes Service (Amazon EKS).

DevOps pipelines involve the continuous integration, delivery, and deployment of cloud infrastructure and applications, which can store and process sensitive data. The increasing adoption of DevOps pipelines for cloud infrastructure and application deployments has made the protection of sensitive data a critical priority for organizations.

Some examples of the types of sensitive data that must be protected in DevOps pipelines are:

  • Credentials: Usernames and passwords used to access cloud resources, databases, and applications.
  • Configuration files: Files that contain settings and configuration data for applications, databases, and other systems.
  • Certificates: TLS certificates used to encrypt communication between systems.
  • Secrets: Any other sensitive data used to access or authenticate with cloud resources, such as private keys, security tokens, or passwords for third-party services.

Unintended access or data disclosure can have serious consequences such as loss of productivity, legal liabilities, financial losses, and reputational damage. It’s crucial to prioritize data protection to help mitigate these risks effectively.

The concept of security of the pipeline encompasses implementing security measures to protect the entire DevOps pipeline—the infrastructure, tools, and processes—from potential security issues. While the concept of security in the pipeline focuses on incorporating security practices and controls directly into the development and deployment processes within the pipeline.

By using Secrets Manager, AWS KMS, and ACM, you can strengthen the security of your DevOps pipelines, safeguard sensitive data, and facilitate secure and compliant application deployments. Our goal is to equip you with the knowledge and tools to establish a secure DevOps environment, providing the integrity of your pipeline infrastructure and protecting your organization’s sensitive data throughout the software delivery process.

Sample application architecture overview

WordPress was chosen as the use case for this DevOps pipeline implementation due to its popularity, open source nature, containerization support, and integration with AWS services. The sample architecture for the WordPress application in the AWS cloud uses the following services:

  • Amazon Route 53: A DNS web service that routes traffic to the correct AWS resource.
  • Amazon CloudFront: A global content delivery network (CDN) service that securely delivers data and videos to users with low latency and high transfer speeds.
  • AWS WAF: A web application firewall that protects web applications from common web exploits.
  • AWS Certificate Manager (ACM): A service that provides SSL/TLS certificates to enable secure connections.
  • Application Load Balancer (ALB): Routes traffic to the appropriate container in Amazon EKS.
  • Amazon Elastic Kubernetes Service (Amazon EKS): A scalable and highly available Kubernetes cluster to deploy containerized applications.
  • Amazon Relational Database Service (Amazon RDS): A managed relational database service that provides scalable and secure databases for applications.
  • AWS Key Management Service (AWS KMS): A key management service that allows you to create and manage the encryption keys used to protect your data at rest.
  • AWS Secrets Manager: A service that provides the ability to rotate, manage, and retrieve database credentials.
  • AWS CodePipeline: A fully managed continuous delivery service that helps to automate release pipelines for fast and reliable application and infrastructure updates.
  • AWS CodeBuild: A fully managed continuous integration service that compiles source code, runs tests, and produces ready-to-deploy software packages.
  • AWS CodeCommit: A secure, highly scalable, fully managed source-control service that hosts private Git repositories.

Before we explore the specifics of the sample application architecture in Figure 1, it’s important to clarify a few aspects of the diagram. While it displays only a single Availability Zone (AZ), please note that the application and infrastructure can be developed to be highly available across multiple AZs to improve fault tolerance. This means that even if one AZ is unavailable, the application remains operational in other AZs, providing uninterrupted service to users.

Figure 1: Sample application architecture

Figure 1: Sample application architecture

The flow of the data protection services in the post and depicted in Figure 1 can be summarized as follows:

First, we discuss securing your pipeline. You can use Secrets Manager to securely store sensitive information such as Amazon RDS credentials. We show you how to retrieve these secrets from Secrets Manager in your DevOps pipeline to access the database. By using Secrets Manager, you can protect critical credentials and help prevent unauthorized access, strengthening the security of your pipeline.

Next, we cover data encryption. With AWS KMS, you can encrypt sensitive data at rest. We explain how to encrypt data stored in Amazon RDS using AWS KMS encryption, making sure that it remains secure and protected from unauthorized access. By implementing KMS encryption, you add an extra layer of protection to your data and bolster the overall security of your pipeline.

Lastly, we discuss securing connections (data in transit) in your WordPress application. ACM is used to manage SSL/TLS certificates. We show you how to provision and manage SSL/TLS certificates using ACM and configure your Amazon EKS cluster to use these certificates for secure communication between users and the WordPress application. By using ACM, you can establish secure communication channels, providing data privacy and enhancing the security of your pipeline.

Note: The code samples in this post are only to demonstrate the key concepts. The actual code can be found on GitHub.

Securing sensitive data with Secrets Manager

In this sample application architecture, Secrets Manager is used to store and manage sensitive data. The AWS CloudFormation template provided sets up an Amazon RDS for MySQL instance and securely sets the master user password by retrieving it from Secrets Manager using KMS encryption.

Here’s how Secrets Manager is implemented in this sample application architecture:

  1. Creating a Secrets Manager secret.
    1. Create a Secrets Manager secret that includes the Amazon RDS database credentials using CloudFormation.
    2. The secret is encrypted using an AWS KMS customer managed key.
    3. Sample code:
      RDSMySQL:
          Type: AWS::RDS::DBInstance
          Properties: 
      		ManageMasterUserPassword: true
      		MasterUserSecret:
              		KmsKeyId: !Ref RDSMySqlSecretEncryption

    The ManageMasterUserPassword: true line in the CloudFormation template indicates that the stack will manage the master user password for the Amazon RDS instance. To securely retrieve the password for the master user, the CloudFormation template uses the MasterUserSecret parameter, which retrieves the password from Secrets Manager. The KmsKeyId: !Ref RDSMySqlSecretEncryption line specifies the KMS key ID that will be used to encrypt the secret in Secrets Manager.

    By setting the MasterUserSecret parameter to retrieve the password from Secrets Manager, the CloudFormation stack can securely retrieve and set the master user password for the Amazon RDS MySQL instance without exposing it in plain text. Additionally, specifying the KMS key ID for encryption adds another layer of security to the secret stored in Secrets Manager.

  2. Retrieving secrets from Secrets Manager.
    1. The secrets store CSI driver is a Kubernetes-native driver that provides a common interface for Secrets Store integration with Amazon EKS. The secrets-store-csi-driver-provider-aws is a specific provider that provides integration with the Secrets Manager.
    2. To set up Amazon EKS, the first step is to create a SecretProviderClass, which specifies the secret ID of the Amazon RDS database. This SecretProviderClass is then used in the Kubernetes deployment object to deploy the WordPress application and dynamically retrieve the secrets from the secret manager during deployment. This process is entirely dynamic and verifies that no secrets are recorded anywhere. The SecretProviderClass is created on a specific app namespace, such as the wp namespace.
    3. Sample code:
      apiVersion: secrets-store.csi.x-k8s.io/v1
      kind: SecretProviderClass
      spec:
        provider: aws
        parameters:
          objects: |
              - objectName: 'rds!db-0x0000-0x0000-0x0000-0x0000-0x0000'
      

When using Secrets manager, be aware of the following best practices for managing and securing Secrets Manager secrets:

  • Use AWS Identity and Access Management (IAM) identity policies to define who can perform specific actions on Secrets Manager secrets, such as reading, writing, or deleting them.
  • Secrets Manager resource policies can be used to manage access to secrets at a more granular level. This includes defining who has access to specific secrets based on attributes such as IP address, time of day, or authentication status.
  • Encrypt the Secrets Manager secret using an AWS KMS key.
  • Using CloudFormation templates to automate the creation and management of Secrets Manager secrets including rotation.
  • Use AWS CloudTrail to monitor access and changes to Secrets Manager secrets.
  • Use CloudFormation hooks to validate the Secrets Manager secret before and after deployment. If the secret fails validation, the deployment is rolled back.

Encrypting data with AWS KMS

Data encryption involves converting sensitive information into a coded form that can only be accessed with the appropriate decryption key. By implementing encryption measures throughout your pipeline, you make sure that even if unauthorized individuals gain access to the data, they won’t be able to understand its contents.

Here’s how data at rest encryption using AWS KMS is implemented in this sample application architecture:

  1. Amazon RDS secret encryption
    1. Encrypting secrets: An AWS KMS customer managed key is used to encrypt the secrets stored in Secrets Manager to ensure their confidentiality during the DevOps build process.
    2. Sample code:
      RDSMySQL:
          Type: AWS::RDS::DBInstance
          Properties:
            ManageMasterUserPassword: true
            MasterUserSecret:
              KmsKeyId: !Ref RDSMySqlSecretEncryption
      
      RDSMySqlSecretEncryption:
          Type: "AWS::KMS::Key"
          Properties:
            KeyPolicy:
              Id: rds-mysql-secret-encryption
              Statement:
                - Sid: Allow administration of the key
                  Effect: Allow
                  "Action": [
                      "kms:Create*",
                      "kms:Describe*",
                      "kms:Enable*",
                      "kms:List*",
                      "kms:Put*",
      					.
      					.
      					.
                  ]
                - Sid: Allow use of the key
                  Effect: Allow
                  "Action": [
                      "kms:Decrypt",
                      "kms:GenerateDataKey",
                      "kms:DescribeKey"
                  ]

  2. Amazon RDS data encryption
    1. Enable encryption for an Amazon RDS instance using CloudFormation. Specify the KMS key ARN in the CloudFormation stack and RDS will use the specified KMS key to encrypt data at rest.
    2. Sample code:
      RDSMySQL:
          Type: AWS::RDS::DBInstance
          Properties:
        KmsKeyId: !Ref RDSMySqlDataEncryption
              StorageEncrypted: true
      
      RDSMySqlDataEncryption:
          Type: "AWS::KMS::Key"
          Properties:
            KeyPolicy:
              Id: rds-mysql-data-encryption
              Statement:
                - Sid: Allow administration of the key
                  Effect: Allow
                  "Action": [
                      "kms:Create*",
                      "kms:Describe*",
                      "kms:Enable*",
                      "kms:List*",
                      "kms:Put*",
      .
      .
      .
                  ]
                - Sid: Allow use of the key
                  Effect: Allow
                  "Action": [
                      "kms:Decrypt",
                      "kms:GenerateDataKey",
                      "kms:DescribeKey"
                  ]

  3. Kubernetes Pods storage
    1. Use encrypted Amazon Elastic Block Store (Amazon EBS) volumes to store configuration data. Create a managed encrypted Amazon EBS volume using the following code snippet, and then deploy a Kubernetes pod with the persistent volume claim (PVC) mounted as a volume.
    2. Sample code:
      kind: StorageClass
      provisioner: ebs.csi.aws.com
      parameters:
        csi.storage.k8s.io/fstype: xfs
        encrypted: "true"
      
      kind: Deployment
      spec:
        volumes:      
            - name: persistent-storage
              persistentVolumeClaim:
                claimName: ebs-claim

  4. Amazon ECR
    1. To secure data at rest in Amazon Elastic Container Registry (Amazon ECR), enable encryption at rest for Amazon ECR repositories using the AWS Management Console or AWS Command Line Interface (AWS CLI). ECR uses AWS KMS to encrypt the data at rest.
    2. Create a KMS key for Amazon ECR and use that key to encrypt the data at rest.
    3. Automate the creation of encrypted ECR repositories and enable encryption at rest using a DevOps pipeline, use CodePipeline to automate the deployment of the CloudFormation stack.
    4. Define the creation of encrypted Amazon ECR repositories as part of the pipeline.
    5. Sample code:
      ECRRepository:
          Type: AWS::ECR::Repository
          Properties: 
            EncryptionConfiguration: 
              EncryptionType: KMS
              KmsKey: !Ref ECREncryption
      
      ECREncryption:
          Type: AWS::KMS::Key
          Properties:
            KeyPolicy:
              Id: ecr-encryption-key
              Statement:
                - Sid: Allow administration of the key
                  Effect: Allow
                  "Action": [
                      "kms:Create*",
                      "kms:Describe*",
                      "kms:Enable*",
                      "kms:List*",
                      "kms:Put*",
      .
      .
      .
       ]
                - Sid: Allow use of the key
                  Effect: Allow
                  "Action": [
                      "kms:Decrypt",
                      "kms:GenerateDataKey",
                      "kms:DescribeKey"
                  ]

AWS best practices for managing encryption keys in an AWS environment

To effectively manage encryption keys and verify the security of data at rest in an AWS environment, we recommend the following best practices:

  • Use separate AWS KMS customer managed KMS keys for data classifications to provide better control and management of keys.
  • Enforce separation of duties by assigning different roles and responsibilities for key management tasks, such as creating and rotating keys, setting key policies, or granting permissions. By segregating key management duties, you can reduce the risk of accidental or intentional key compromise and improve overall security.
  • Use CloudTrail to monitor AWS KMS API activity and detect potential security incidents.
  • Rotate KMS keys as required by your regulatory requirements.
  • Use CloudFormation hooks to validate KMS key policies to verify that they align with organizational and regulatory requirements.

Following these best practices and implementing encryption at rest for different services such as Amazon RDS, Kubernetes Pods storage, and Amazon ECR, will help ensure that data is encrypted at rest.

Securing communication with ACM

Secure communication is a critical requirement for modern environments and implementing it in a DevOps pipeline is crucial for verifying that the infrastructure is secure, consistent, and repeatable across different environments. In this WordPress application running on Amazon EKS, ACM is used to secure communication end-to-end. Here’s how to achieve this:

  1. Provision TLS certificates with ACM using a DevOps pipeline
    1. To provision TLS certificates with ACM in a DevOps pipeline, automate the creation and deployment of TLS certificates using ACM. Use AWS CloudFormation templates to create the certificates and deploy them as part of infrastructure as code. This verifies that the certificates are created and deployed consistently and securely across multiple environments.
    2. Sample code:
      DNSDomainCertificate:
          Type: AWS::CertificateManager::Certificate
          Properties:
            DomainName: !Ref DNSDomainName
            ValidationMethod: 'DNS'
      
      DNSDomainName:
          Description: dns domain name 
          TypeM: String
          Default: "example.com"

  2. Provisioning of ALB and integration of TLS certificate using AWS ALB Ingress Controller for Kubernetes
    1. Use a DevOps pipeline to create and configure the TLS certificates and ALB. This verifies that the infrastructure is created consistently and securely across multiple environments.
    2. Sample code:
      kind: Ingress
      metadata:
        annotations:
          alb.ingress.kubernetes.io/scheme: internet-facing
          alb.ingress.kubernetes.io/certificate-arn: arn:aws:acm:us-east-1:000000000000:certificate/0x0000-0x0000-0x0000-0x0000-0x0000
          alb.ingress.kubernetes.io/listen-ports: '[{"HTTPS":443}]'
          alb.ingress.kubernetes.io/security-groups:  sg-0x00000x0000,sg-0x00000x0000
      spec:
        ingressClassName: alb

  3. CloudFront and ALB
    1. To secure communication between CloudFront and the ALB, verify that the traffic from the client to CloudFront and from CloudFront to the ALB is encrypted using the TLS certificate.
    2. Sample code:
      CloudFrontDistribution:
          Type: AWS::CloudFront::Distribution
          Properties:
            DistributionConfig:
              Origins:
                - DomainName: !Ref ALBDNSName
                  Id: !Ref ALBDNSName
                  CustomOriginConfig:
                    HTTPSPort: '443'
                    OriginProtocolPolicy: 'https-only'
                    OriginSSLProtocols:
                      - LSv1
      	    ViewerCertificate:
      AcmCertificateArn: !Sub 'arn:aws:acm:${AWS::Region}:${AWS::AccountId}:certificate/${ACMCertificateIdentifier}'
                  SslSupportMethod:  'sni-only'
                  MinimumProtocolVersion: 'TLSv1.2_2021'
      
      ALBDNSName:
          Description: alb dns name
          Type: String
          Default: "k8s-wp-ingressw-x0x0000x000-x0x0000x000.us-east-1.elb.amazonaws.com"

  4. ALB to Kubernetes Pods
    1. To secure communication between the ALB and the Kubernetes Pods, use the Kubernetes ingress resource to terminate SSL/TLS connections at the ALB. The ALB sends the PROTO metadata http connection header to the WordPress web server. The web server checks the incoming traffic type (http or https) and enables the HTTPS connection only hereafter. This verifies that pod responses are sent back to ALB only over HTTPS.
    2. Additionally, using the X-Forwarded-Proto header can help pass the original protocol information and help avoid issues with the $_SERVER[‘HTTPS’] variable in WordPress.
    3. Sample code:
      define('WP_HOME','https://example.com/');
      define('WP_SITEURL','https://example.com/');
      
      define('FORCE_SSL_ADMIN', true);
      if (isset($_SERVER['HTTP_X_FORWARDED_PROTO']) && strpos($_SERVER['HTTP_X_FORWARDED_PROTO'], 'https') !== false) {
          $_SERVER['HTTPS'] = 'on';

  5. Kubernetes Pods to Amazon RDS
    1. To secure communication between the Kubernetes Pods in Amazon EKS and the Amazon RDS database, use SSL/TLS encryption on the database connection.
    2. Configure an Amazon RDS MySQL instance with enhanced security settings to verify that only TLS-encrypted connections are allowed to the database. This is achieved by creating a DB parameter group with a parameter called require_secure_transport set to ‘1‘. The WordPress configuration file is also updated to enable SSL/TLS communication with the MySQL database. Then enable the TLS flag on the MySQL client and the Amazon RDS public certificate is passed to ensure that the connection is encrypted using the TLS_AES_256_GCM_SHA384 protocol. The sample code that follows focuses on enhancing the security of the RDS MySQL instance by enforcing encrypted connections and configuring WordPress to use SSL/TLS for communication with the database.
    3. Sample code:
      RDSDBParameterGroup:
          Type: 'AWS::RDS::DBParameterGroup'
          Properties:
            DBParameterGroupName: 'rds-tls-custom-mysql'
            Parameters:
              require_secure_transport: '1'
      
      RDSMySQL:
          Type: AWS::RDS::DBInstance
          Properties:
            DBName: 'wordpress'
            DBParameterGroupName: !Ref RDSDBParameterGroup
      
      wp-config-docker.php:
      // Enable SSL/TLS between WordPress and MYSQL database
      define('MYSQL_CLIENT_FLAGS', MYSQLI_CLIENT_SSL);//This activates SSL mode
      define('MYSQL_SSL_CA', '/usr/src/wordpress/amazon-global-bundle-rds.pem');

In this architecture, AWS WAF is enabled at CloudFront to protect the WordPress application from common web exploits. AWS WAF for CloudFront is recommended and use AWS managed WAF rules to verify that web applications are protected from common and the latest threats.

Here are some AWS best practices for securing communication with ACM:

  • Use SSL/TLS certificates: Encrypt data in transit between clients and servers. ACM makes it simple to create, manage, and deploy SSL/TLS certificates across your infrastructure.
  • Use ACM-issued certificates: This verifies that your certificates are trusted by major browsers and that they are regularly renewed and replaced as needed.
  • Implement certificate revocation: Implement certificate revocation for SSL/TLS certificates that have been compromised or are no longer in use.
  • Implement strict transport security (HSTS): This helps protect against protocol downgrade attacks and verifies that SSL/TLS is used consistently across sessions.
  • Configure proper cipher suites: Configure your SSL/TLS connections to use only the strongest and most secure cipher suites.

Monitoring and auditing with CloudTrail

In this section, we discuss the significance of monitoring and auditing actions in your AWS account using CloudTrail. CloudTrail is a logging and tracking service that records the API activity in your AWS account, which is crucial for troubleshooting, compliance, and security purposes. Enabling CloudTrail in your AWS account and securely storing the logs in a durable location such as Amazon Simple Storage Service (Amazon S3) with encryption is highly recommended to help prevent unauthorized access. Monitoring and analyzing CloudTrail logs in real-time using CloudWatch Logs can help you quickly detect and respond to security incidents.

In a DevOps pipeline, you can use infrastructure-as-code tools such as CloudFormation, CodePipeline, and CodeBuild to create and manage CloudTrail consistently across different environments. You can create a CloudFormation stack with the CloudTrail configuration and use CodePipeline and CodeBuild to build and deploy the stack to different environments. CloudFormation hooks can validate the CloudTrail configuration to verify it aligns with your security requirements and policies.

It’s worth noting that the aspects discussed in the preceding paragraph might not apply if you’re using AWS Organizations and the CloudTrail Organization Trail feature. When using those services, the management of CloudTrail configurations across multiple accounts and environments is streamlined. This centralized approach simplifies the process of enforcing security policies and standards uniformly throughout the organization.

By following these best practices, you can effectively audit actions in your AWS environment, troubleshoot issues, and detect and respond to security incidents proactively.

Complete code for sample architecture for deployment

The complete code repository for the sample WordPress application architecture demonstrates how to implement data protection in a DevOps pipeline using various AWS services. The repository includes both infrastructure code and application code that covers all aspects of the sample architecture and implementation steps.

The infrastructure code consists of a set of CloudFormation templates that define the resources required to deploy the WordPress application in an AWS environment. This includes the Amazon Virtual Private Cloud (Amazon VPC), subnets, security groups, Amazon EKS cluster, Amazon RDS instance, AWS KMS key, and Secrets Manager secret. It also defines the necessary security configurations such as encryption at rest for the RDS instance and encryption in transit for the EKS cluster.

The application code is a sample WordPress application that is containerized using Docker and deployed to the Amazon EKS cluster. It shows how to use the Application Load Balancer (ALB) to route traffic to the appropriate container in the EKS cluster, and how to use the Amazon RDS instance to store the application data. The code also demonstrates how to use AWS KMS to encrypt and decrypt data in the application, and how to use Secrets Manager to store and retrieve secrets. Additionally, the code showcases the use of ACM to provision SSL/TLS certificates for secure communication between the CloudFront and the ALB, thereby ensuring data in transit is encrypted, which is critical for data protection in a DevOps pipeline.

Conclusion

Strengthening the security and compliance of your application in the cloud environment requires automating data protection measures in your DevOps pipeline. This involves using AWS services such as Secrets Manager, AWS KMS, ACM, and AWS CloudFormation, along with following best practices.

By automating data protection mechanisms with AWS CloudFormation, you can efficiently create a secure pipeline that is reproducible, controlled, and audited. This helps maintain a consistent and reliable infrastructure.

Monitoring and auditing your DevOps pipeline with AWS CloudTrail is crucial for maintaining compliance and security. It allows you to track and analyze API activity, detect any potential security incidents, and respond promptly.

By implementing these best practices and using data protection mechanisms, you can establish a secure pipeline in the AWS cloud environment. This enhances the overall security and compliance of your application, providing a reliable and protected environment for your deployments.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Magesh Dhanasekaran

Magesh Dhanasekaran

Magesh has significant experience in the cloud security space especially in data protection, threat detection and security governance, risk & compliance domain. Magesh has a track record in providing Information Security consulting service to financial industry and government agencies in Australia. He is using his extensive experience in cloud security architecture, digital transformation, and secure application development practice to provide security advisory on AWS products and services to WWPS Federal Financial Customers. Magesh currently holds cybersecurity industry certifications such as ISC2’s CISSP, ISACA’s CISM, CompTIA Security+ and AWS Solution Architect / Security Specialty Certification.

Karna Thandapani

Karna Thandapani

Karna is a Cloud Consultant with extensive experience in DevOps/DevSecOps and application development activities as a Developer. Karna has in-depth knowledge and hands-on experience in the major AWS services (Cloudformation, EC2, Lambda, Serverless, Step Functions, Glue, API Gateway, ECS, EKS, LB, AutoScaling, Route53, etc.,)and holding Developer Associate, Solutions Architect Associate, and DevOps Engineer Professional.

Automate Cedar policy validation with AWS developer tools

Post Syndicated from Pontus Palmenäs original https://aws.amazon.com/blogs/security/automate-cedar-policy-validation-with-aws-developer-tools/

Cedar is an open-source language that you can use to authorize policies and make authorization decisions based on those policies. AWS security services including AWS Verified Access and Amazon Verified Permissions use Cedar to define policies. Cedar supports schema declaration for the structure of entity types in those policies and policy validation with that schema.

In this post, we show you how to use developer tools on AWS to implement a build pipeline that validates the Cedar policy files against a schema and runs a suite of tests to isolate the Cedar policy logic. As part of the walkthrough, you will introduce a subtle policy error that impacts permissions to observe how the pipeline tests catch the error. Detecting errors earlier in the development lifecycle is often referred to as shifting left. When you shift security left, you can help prevent undetected security issues during the application build phase.

Scenario

This post extends a hypothetical photo sharing application from the Cedar policy language in action workshop. By using that app, users organize their photos into albums and share them with groups of users. Figure 1 shows the entities from the photo application.

Figure 1: Photo application entities

Figure 1: Photo application entities

For the purpose of this post, the important requirements are that user JohnDoe has view access to the album JaneVacation, which contains two photos that user JaneDoe owns:

  • Photo sunset.jpg has a contest label (indicating that the role PhotoJudge has view access)
  • Photo nightclub.jpg has a private label (indicating that only the owner has access)

Cedar policies separate application permissions from the code that retrieves and displays photos. The following Cedar policy explicitly permits the principal of user JohnDoe to take the action viewPhoto on resources in the album JaneVacation.

permit (
  principal == PhotoApp::User::"JohnDoe",
  action == PhotoApp::Action::"viewPhoto",
  resource in PhotoApp::Album::"JaneVacation"
);

The following Cedar policy forbids non-owners from accessing photos labeled as private, even if other policies permit access. In our example, this policy prevents John Doe from viewing the nightclub.jpg photo (denoted by an X in Figure 1).

forbid (
  principal,
  action,
  resource in PhotoApp::Application::"PhotoApp"
)
when { resource.labels.contains("private") }
unless { resource.owner == principal };

A Cedar authorization request asks the question: Can this principal take this action on this resource in this context? The request also includes attribute and parent information for the entities. If an authorization request is made with the following test data, against the Cedar policies and entity data described earlier, the authorization result should be DENY.

{
  "principal": "PhotoApp::User::\"JohnDoe\"",
  "action": "PhotoApp::Action::\"viewPhoto\"",
  "resource": "PhotoApp::Photo::\"nightclub.jpg\"",
  "context": {}
}

The project test suite uses this and other test data to validate the expected behaviors when policies are modified. An error intentionally introduced into the preceding forbid policy lets the first policy satisfy the request and ALLOW access. That unexpected test result compared to the requirements fails the build.

Developer tools on AWS

With AWS developer tools, you can host code and build, test, and deploy applications and infrastructure. AWS CodeCommit hosts the Cedar policies and a test suite, AWS CodeBuild runs the tests, and AWS CodePipeline automatically runs the CodeBuild job when a CodeCommit repository state change event occurs.

In the following steps, you will create a pipeline, commit policies and tests, run a passing build, and observe how a policy error during validation fails a test case.

Prerequisites

To follow along with this walkthrough, make sure to complete the following prerequisites:

Set up the local environment

The first step is to set up your local environment.

To set up the local environment

  1. Using Git, clone the GitHub repository for this post:
  2. git clone [email protected]:aws-samples/cedar-policy-validation-pipeline.git

  3. Before you commit this source code to a CodeCommit repository, run the test suite locally; this can help you shorten the feedback loop. To run the test suite locally, choose one of the following options:
  4. Option 1: Install Rust and compile the Cedar CLI binary

    1. Install Rust by using the rustup tool.
    2. curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh -s -- -y

    3. Compile the Cedar CLI (version 2.4.2) binary by using cargo.
    4. cargo install [email protected]

    5. Run the cedar_testrunner.sh script, which tests authorize requests by using the Cedar CLI.
    6. cd policystore/tests && ./cedar_testrunner.sh

    Option 2: Run the CodeBuild agent

    1. Locally evaluate the buildspec.yml inside a CodeBuild container image by using the codebuild_build.sh script from aws-codebuild-docker-images with the following parameters:
    2. ./codebuild_build.sh -i public.ecr.aws/codebuild/amazonlinux2-x86_64-standard:5.0 -a .codebuild

Project structure

The policystore directory contains one Cedar policy for each .cedar file. The Cedar schema is defined in the cedarschema.json file. A tests subdirectory contains a cedarentities.json file that represents the application data; its subdirectories (for example, album JaneVacation) represent the test suites. The test suite directories contain individual tests inside their ALLOW and DENY subdirectories, each with one or more JSON files that contain the authorization request that Cedar will evaluate against the policy set. A README file in the tests directory provides a summary of the test cases in the suite.

The cedar_testrunner.sh script runs the Cedar CLI to perform a validate command for each .cedar file against the Cedar schema, outputting either PASS or ERROR. The script also performs an authorize command on each test file, outputting either PASS or FAIL depending on whether the results match the expected authorization decision.

Set up the CodePipeline

In this step, you use AWS CloudFormation to provision the services used in the pipeline.

To set up the pipeline

  1. Navigate to the directory of the cloned repository.

    cd cedar-policy-validation-pipeline

  2. Create a new CloudFormation stack from the template.
    aws cloudformation deploy \
    --template-file template.yml \
    --stack-name cedar-policy-validation \
    --capabilities CAPABILITY_NAMED_IAM

  3. Wait for the message Successfully created/updated stack.

Invoke CodePipeline

The next step is to commit the source code to a CodeCommit repository, and then configure and invoke CodePipeline.

To invoke CodePipeline

  1. Add an additional Git remote named codecommit to the repository that you previously cloned. The following command points the Git remote to the CodeCommit repository that CloudFormation created. The CedarPolicyRepoCloneUrl stack output is the HTTPS clone URL. Replace it with CedarPolicyRepoCloneGRCUrl to use the HTTPS (GRC) clone URL when you connect to CodeCommit with git-remote-codecommit.

    git remote add codecommit $(aws cloudformation describe-stacks --stack-name cedar-policy-validation --query 'Stacks[0].Outputs[?OutputKey==`CedarPolicyRepoCloneUrl`].OutputValue' --output text)

  2. Push the code to the CodeCommit repository. This starts a pipeline run.

    git push codecommit main

  3. Check the progress of the pipeline run.
    aws codepipeline get-pipeline-execution \
    --pipeline-name cedar-policy-validation \
    --pipeline-execution-id $(aws codepipeline list-pipeline-executions --pipeline-name cedar-policy-validation --query 'pipelineExecutionSummaries[0].pipelineExecutionId' --output text) \
    --query 'pipelineExecution.status' --output text

The build installs Rust in CodePipeline in your account and compiles the Cedar CLI. After approximately four minutes, the pipeline run status shows Succeeded.

Refactor some policies

This photo sharing application sample includes overlapping policies to simulate a refactoring workflow, where after changes are made, the test suite continues to pass. The DoePhotos.cedar and JaneVacation.cedar static policies are replaced by the logically equivalent viewPhoto.template.cedar policy template and two template-linked policies defined in cedartemplatelinks.json. After you delete the extra policies, the passing tests illustrate a successful refactor with the same expected application permissions.

To refactor policies

  1. Delete DoePhotos.cedar and JaneVacation.cedar.
  2. Commit the change to the repository.
    git add .
    git commit -m "Refactor some policies"
    git push codecommit main

  3. Check the pipeline progress. After about 20 seconds, the pipeline status shows Succeeded.

The second pipeline build runs quicker because the build specification is configured to cache a version of the Cedar CLI. Note that caching isn’t implemented in the local testing described in Option 2 of the local environment setup.

Break the build

After you confirm that you have a working pipeline that validates the Cedar policies, see what happens when you commit an invalid Cedar policy.

To break the build

  1. Using a text editor, open the file policystore/Photo-labels-private.cedar.
  2. In the when clause, change resource.labels to resource.label (removing the “s”). This policy syntax is valid, but no longer validates against the Cedar schema.
  3. Commit the change to the repository.
    git add .
    git commit -m "Break the build"
    git push codecommit main

  4. Sign in to the AWS Management Console and open the CodePipeline console.
  5. Wait for the Most recent execution field to show Failed.
  6. Select the pipeline and choose View in CodeBuild.
  7. Choose the Reports tab, and then choose the most recent report.
  8. Review the report summary, which shows details such as the total number of Passed and Failed/Error test case totals, and the pass rate, as shown in Figure 2.
  9. Figure 2: CodeBuild test report summary

    Figure 2: CodeBuild test report summary

  10. To get the error details, in the Details section, select the Test case called validate Photo-labels-private.cedar that has a Status of Error.
  11. Figure 3: CodeBuild test report test cases

    Figure 3: CodeBuild test report test cases

    That single policy change resulted in two test cases that didn’t pass. The detailed error message shown in Figure 4 is the output from the Cedar CLI. When the policy was validated against the schema, Cedar found the invalid attribute label on the entity type PhotoApp::Photo. The Failed message of unexpected ALLOW occurred because the label attribute typo prevented the forbid policy from matching and producing a DENY result. Each of these tests helps you avoid deploying invalid policies.

    Figure 4: CodeBuild test case error message

    Figure 4: CodeBuild test case error message

Clean up

To avoid ongoing costs and to clean up the resources that you deployed in your AWS account, complete the following steps:

To clean up the resources

  1. Open the Amazon S3 console, select the bucket that begins with the phrase cedar-policy-validation-codepipelinebucket, and Empty the bucket.
  2. Open the CloudFormation console, select the cedar-policy-validation stack, and then choose Delete.
  3. Open the CodeBuild console, choose Build History, filter by cedar-policy-validation, select all results, and then choose Delete builds.

Conclusion

In this post, you learned how to use AWS developer tools to implement a pipeline that automatically validates and tests when Cedar policies are updated and committed to a source code repository. Using this approach, you can detect invalid policies and potential application permission errors earlier in the development lifecycle and before deployment.

To learn more about the Cedar policy language, see the Cedar Policy Language Reference Guide or browse the source code at the cedar-policy organization on GitHub. For real-time validation of Cedar policies and schemas, install the Cedar policy language for Visual Studio Code extension.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Amazon Verified Permissions re:Post or contact AWS Support.

Pontus Palmenas

Pontus Palmenäs

Pontus is a Startup Solutions Architect based in Stockholm, Sweden, where he is helping customers in healthcare and life sciences and FinTech. He is passionate about all things security. Outside of work, he enjoys making electronic music in his home studio and spending quality time with his family.

Kevin Hakanson

Kevin Hakanson

Kevin is a Senior Solutions Architect for AWS World Wide Public Sector based in Minnesota. He works with EdTech and GovTech customers to ideate, design, validate, and launch products using cloud-native technologies and modern development practices. When not staring at a computer screen, he is probably staring at another screen, either watching TV or playing video games with his family.

Best Practices for Prompt Engineering with Amazon CodeWhisperer

Post Syndicated from Brendan Jenkins original https://aws.amazon.com/blogs/devops/best-practices-for-prompt-engineering-with-amazon-codewhisperer/

Generative AI coding tools are changing the way developers accomplish day-to-day development tasks. From generating functions to creating unit tests, these tools have helped customers accelerate software development. Amazon CodeWhisperer is an AI-powered productivity tools for the IDE and command line that helps improve developer productivity by providing code recommendations based on developers’ natural language comments and surrounding code. With CodeWhisperer, developers can simply write a comment that outlines a specific task in plain English, such as “create a lambda function to upload a file to S3.”

When writing these input prompts to CodeWhisperer like the natural language comments, one important concept is prompt engineering. Prompt engineering is the process of refining interactions with large language models (LLMs) in order to better refine the output of the model. In this case, we want to refine our prompts provided to CodeWhisperer to produce better code output.

In this post, we’ll explore how to take advantage of CodeWhisperer’s capabilities through effective prompt engineering in Python. A well-crafted prompt lets you tap into the tool’s full potential to boost your productivity and help generate the correct code for your use case. We’ll cover prompt engineering best practices like writing clear, specific prompts and providing helpful context and examples. We’ll also discuss how to iteratively refine prompts to produce better results.

Prompt Engineering with CodeWhisperer

We will demonstrate the following best practices when it comes to prompt engineering with CodeWhisperer.

  • Keep your prompt specific and concise
  • Additional context in prompts
  • Utilizing multiple comments
  • Context taken from comments and code
  • Generating unit tests with cross file context
  • Prompts with cross file context

Prerequisites

The following prerequisites are required to experiment locally:

CodeWhisperer User Actions

Reference the following user actions documentation for CodeWhisperer user actions according to your IDE. In this documentation, you will see how to accept a recommendation, cycle through recommendation options, reject a recommendation, and manually trigger CodeWhisperer.

Keep prompts specific & concise

In this section, we will cover keeping your prompt specific and concise. When crafting prompts for CodeWhisperer, conciseness while maintaining objectives in your prompt is important.  Overly complex prompts lead to poor results. A good prompt contains just enough information to convey the request clearly and concisely. For example, if you prompt CodeWhisperer “create a function that eliminates duplicates lines in a text file”. This is an example of a specific and concise prompt. On the other hand, a prompt such as “create a function to look for lines of code that are seen multiple times throughout the file and delete them” may be unclear and overly wordy. In summary, focused, straightforward prompts helps CodeWhisperer understand exactly what you want and provide better outputs.

In this example, we would like to write a function in Python that will open a CSV file and store the contents into a dictionary. We will use the following simple and concise prompt that will guide CodeWhisperer to generate recommendations. Please use the left/right arrow key to cycle through the various recommendations before you hit tab to accept the recommendation.

Example 1:

Sample comment:

#load the csv file content in a dictionary

Sample solution:

#load the csv file content in a dictionary
import csv
def csv_to_dict(csv_file):
    with open(csv_file, 'r') as f:
        reader = csv.DictReader(f)
        return list(reader)

Simple and concise prompts are crucial in prompt engineering because they help CodeWhisperer understand the key information without confusion from extraneous details. Simplicity and brevity enable faster iteration and allow prompts to maximize impact within character limits.

Additional context in prompts

In this section, we will cover how additional context can aid in prompt engineering. While specific and concise prompts are crucial, some additional context can aid CodeWhisperer comprehension. Concrete examples also guide CodeWhisperer if it struggles to infer expectations from just a brief prompt.

In this example, we would like to add additional context to Example 1 where we stored the CSV file content into a dictionary. Now, we have additional requirements to store the csv file content in alphabetical order and return the list keys from the dictionary. Take a look at the sample prompt below. Judicious context helps CodeWhisperer to produce higher-quality, tailored results.

Example 2:

Sample comment:

#load the csv file content in a dictionary in alphabetical order and return the list of keys

Sample solution:

#load the csv file content in a dictionary in alphabetical order and return the list of keys
import csv
def csv_to_dict(file_name):
    def read_csv_file(file_name):
    with open(file_name, 'r') as csv_file:
        csv_reader = csv.DictReader(csv_file)
        csv_dict = {}
        for row in csv_reader:
            csv_dict[row['name']] = row
            return csv_dict

Providing additional context through background details and examples can be beneficial when crafting prompts for CodeWhisperer, as long as the extra information adds useful clarity rather than obscuring the core request. The right balance of brevity and pointed contextual signals can help CodeWhisperer generate more tailored, high-quality results.

Utilizing multiple comments

In this section, we will cover how multiple comments can be a useful technique in prompt engineering. When used strategically, multiple comments allow prompt engineers to offer more context without sacrificing brevity or cluttering the prompt.

Say we would like to open a CSV file and return the list of lines in alphabetical order, remove duplicate lines, and insert a period at the end of each line from the CSV file. Take a look at the sample CodeWhisperer prompt below. Notice how you can break up multiple requirements into separate comments.

Example 3:

Sample comment:

#open a csv file and return a list of lines in alphabetical order
#Remove duplicate lines
#Insert a period at the end of each line

Sample solution:

#open a csv file and return a list of lines in alphabetical order
#Remove duplicate lines
#Insert a period at the end of each line
def open_csv(filename):
    with open(filename) as f:
        lines = f.readlines()
        lines = list(set(lines))
        lines = sorted(lines)
        for i in range(len(lines)):
            lines[i] = lines[i].rstrip() + '.'
    return lines

Multiple comments allow prompt engineers to add extended context and guidance for CodeWhisperer while keeping prompts succinct.

Context taken from comments and code

In this section, we will cover how CodeWhisperer’s context goes beyond just your comment and also looks at the surrounding code, including other functions, imports, and more. This broader context helps guide CodeWhisperer towards implementing the use case you intend with your comment.

We will now see how additional code in our project affects the responses. This time around, we will import the Pandas library to see how it effects our recommendation as compared to the previous section.

Example 4:

Sample Comment:

import pandas as pd
#open a csv file and return a list of lines in alphabetical order
#Insert a period at the end of each line
#Replace duplicate lines with a single line

Sample solution:

import pandas as pd
#open a csv file and return a list of lines in alphabetical order
#Insert a period at the end of each line
#Replace duplicate lines with a single line
def open_csv(filename):
    df = pd.read_csv(filename)
    df = df.sort_values(by='line')
    df = df.drop_duplicates(subset='line')
    df['line'] = df['line'] + '.'
    return df['line'].tolist()

By seeing Pandas imported, CodeWhisperer understands our intent is likely to leverage it in the solution. This allows it to provide a more relevant recommendation using Pandas functions like read_csv(), sort_values(), and drop_duplicates().

Overall, surrounding code context gives CodeWhisperer additional clues for the implementation you have in mind with your high-level instructions.

Prompts with cross file context

In the previous section, we saw how we were able to utilize the surrounding code that CodeWhisperer takes in as context to generate a function for our use case. In this section, we will use that same concept to generate unit tests for the function we’ve built utilizing CodeWhisperers cross file context capability. This section will demonstrate how we can use cross file context with our prompts for use cases like test driven development.

In this example, we will prompt CodeWhisperer to write a comment referencing the open_csv function in order to write unit tests. In this case, there will be a new python file in the project directory for unit testing. We will assume the file we have been working out of is “example4.py”, and the new file is “unittest.py”. We will incorporate the following comments in “unittest.py”.

Example 5:

Sample Comment in unittest.py:

#create unit tests for the open_csv function from example4.py file

Sample solution in unittest.py:

#create unit tests for the open_csv function from example4.py file
class TestOpenCsv(unittest.TestCase):
   def test_open_csv(self):
       self.assertEqual(open_csv('example4.csv'), ['a.', 'b.', 'c.'])
       self.assertEqual(open_csv('example4.csv'), ['a.', 'b.', 'c.', 'd.'])

Notice how CodeWhisperer is using context from one file to generate code recommendation in another file. By specifying the open_csv function within the comment of the “unittest.py”, CodeWhisperer was able to analyze the function, understand its purpose and interface, and generate a set of basic unit tests to validate it. With our prompts, we were able to utilize CodeWhisperers cross file context to help us generate unit tests.

Chain of thought prompting

Chain of thought prompting is a prompt engineering technique that allows large language models (LLMs) to have more natural, contextual outputs by linking multiple prompts together to solve a complex problem. In regard to CodeWhisperer, we can use this technique to break a very complex coding task down into smaller steps, allowing CodeWhisperer to provide more accurate suggestions to the use case.

In this example, we will examine a code snippet generated by CodeWhisperer that contains multiple comments. Our intention is to prompt the user to input a filename, ensure it’s a csv and alphanumeric, then process it with the logging.info method. We will analyze the output using both the chain of thought approach and a single comment.

Example 6:

Chain of thought prompt approach:

Comment 1 – “Take a user’s input using the input() function and store it in a variable called filename”

import logging
# Take a users input using the input() function and store it in a variable called filename
filename = input("Enter the name of the file you want to read: ")

Comment 2 – create a function that will take a filename as an input

import logging
# Take a users input using the input() function and store it in a variable called filename
filename = input("Enter the name of the file you want to read: ")

#create a function that will take a filename as an input
def open_file(filename):

Comment 3 – validate the input using the isalnum() method and ensure the file ends in .csv then process the file using logging.info()

import logging
# Take a users input using the input() function and store it in a variable called filename
filename = input("Enter the name of the file you want to read: ")

#create a function that will take a filename as an input
def open_file(filename):
    #validate the input using the isalnum() method and ensure the file ends in .csv then process the file using logging.info() 
    if filename.isalnum() and filename.endswith('.csv'):
        lines = open_csv(filename)
        logging.info(lines)
        return lines
    else:
        print('Invalid file name')
        return None

Single prompt approach:

import logging
'''
Using the input() function and store it in a variable called filename and create a function 
that will validate the input using the isalnum() method and ensure the file ends in .csv then process 
the file accordingly. 
'''
def validate_file(filename):
    if filename.isalnum() and filename.endswith('.csv'):
        return True
    else:
        return False

When analyzing these side-by-side, we see that with the chain of thought prompt approach, we used multiple comments to allow CodeWhisperer to implement all our requirements including the user input, input validation, .csv verification, and logging as we broke it down into steps for CodeWhisperer to implement. On the other hand, in the case where we had a single comment implementing multiple requirements, it didn’t take all the requirements into account for this slightly more complex problem.

In conclusion, chain of thought prompting allows large language models like CodeWhisperer to produce more accurate code pertaining to the use case by breaking down complex problems into logical steps. Guiding the model through comments and prompts helps it focus on each part of the task sequentially. This results in code that is more accurate to the desired functionality compared to a single broad prompt.

Conclusion

Effective prompt engineering is key to getting the most out of powerful AI coding assistants like Amazon CodeWhisperer. Following prompt best practices, we’ve covered like using clear language, providing context, and iteratively refining prompts can help CodeWhisperer generate high-quality code tailored to your specific needs. Analyzing all the code options CodeWhisperer provides you flexibility to select the optimal approach.

About the authors:

Brendan Jenkins

Brendan Jenkins is a Solutions Architect at Amazon Web Services (AWS) working with Enterprise AWS customers providing them with technical guidance and helping achieve their business goals. He has an area of specialization in DevOps and Machine Learning technology.

Riya Dani

Riya Dani is a Solutions Architect at Amazon Web Services (AWS), responsible for helping Enterprise customers on their journey in the cloud. She has a passion for learning and holds a Bachelor’s and Master’s degree from Virginia Tech in Computer Science with focus in Deep Learning. In her free time, she enjoys staying active and reading.

Best Practices to help secure your container image build pipeline by using AWS Signer

Post Syndicated from Jorge Castillo original https://aws.amazon.com/blogs/security/best-practices-to-help-secure-your-container-image-build-pipeline-by-using-aws-signer/

AWS Signer is a fully managed code-signing service to help ensure the trust and integrity of your code. It helps you verify that the code comes from a trusted source and that an unauthorized party has not accessed it. AWS Signer manages code signing certificates and public and private keys, which can reduce the overhead of your public key infrastructure (PKI) management. It also provides a set of features to simplify lifecycle management of your keys and certificates so that you can focus on signing and verifying your code.

In June 2023, AWS announced Container Image Signing with AWS Signer and Amazon EKS, a new capability that gives you native AWS support for signing and verifying container images stored in Amazon Elastic Container Registry (Amazon ECR).

Containers and AWS Lambda functions are popular serverless compute solutions for applications built on the cloud. By using AWS Signer, you can verify that the software running in these workloads originates from a trusted source.

In this blog post, you will learn about the benefits of code signing for software security, governance, and compliance needs. Flexible continuous integration and continuous delivery (CI/CD) integration, management of signing identities, and native integration with other AWS services can help you simplify code security through automation.

Background

Code signing is an important part of the software supply chain. It helps ensure that the code is unaltered and comes from an approved source.

To automate software development workflows, organizations often implement a CI/CD pipeline to push, test, and deploy code effectively. You can integrate code signing into the workflow to help prevent untrusted code from being deployed, as shown in Figure 1. Code signing in the pipeline can provide you with different types of information, depending on how you decide to use the functionality. For example, you can integrate code signing into the build stage to attest that the code was scanned for vulnerabilities, had its software bill of materials (SBOM) approved internally, and underwent unit and integration testing. You can also use code signing to verify who has pushed or published the code, such as a developer, team, or organization. You can verify each of these steps separately by including multiple signing stages in the pipeline. For more information on the value provided by container image signing, see Cryptographic Signing for Containers.

Figure 1: Security IN the pipeline

Figure 1: Security IN the pipeline

In the following section, we will walk you through a simple implementation of image signing and its verification for Amazon Elastic Kubernetes Service (Amazon EKS) deployment. The signature attests that the container image went through the pipeline and came from a trusted source. You can use this process in more complex scenarios by adding multiple AWS CodeBuild code signing stages that make use of various AWS Signer signing profiles.

Services and tools

In this section, we discuss the various AWS services and third-party tools that you need for this solution.

CI/CD services

For the CI/CD pipeline, you will use the following AWS services:

  • AWS CodePipeline — a fully managed continuous delivery service that you can use to automate your release pipelines for fast and reliable application and infrastructure updates.
  • AWS CodeCommit — a fully managed source control service that hosts secure Git-based repositories.
  • AWS Signer — a fully managed code-signing service that you can use to help ensure the trust and integrity of your code.
  • AWS CodeBuild — A fully managed continuous integration service that compiles source code, runs tests, and produces software packages that are ready to deploy.

Container services

You will use the following AWS services for containers for this walkthrough:

  • Amazon EKS — a managed Kubernetes service to run Kubernetes in the AWS Cloud and on-premises data centers.
  • Amazon ECR — a fully managed container registry for high-performance hosting, so that you can reliably deploy application images and artifacts anywhere.

Verification tools

The following are publicly available sign verification tools that we integrated into the pipeline for this post, but you could integrate other tools that meet your specific requirements.

  • Notation — A publicly available Notary project within the Cloud Native Computing Foundation (CNCF). With contributions from AWS and others, Notary is an open standard and client implementation that allows for vendor-specific plugins for key management and other integrations. AWS Signer manages signing keys, key rotation, and PKI management for you, and is integrated with Notation through a curated plugin that provides a simple client-based workflow.
  • Kyverno — A publicly available policy engine that is designed for Kubernetes.

Solution overview

Figure 2: Solution architecture

Figure 2: Solution architecture

Here’s how the solution works, as shown in Figure 2:

  1. Developers push Dockerfiles and application code to CodeCommit. Each push to CodeCommit starts a pipeline hosted on CodePipeline.
  2. CodeBuild packages the build, containerizes the application, and stores the image in the ECR registry.
  3. CodeBuild retrieves a specific version of the image that was previously pushed to Amazon ECR. AWS Signer and Notation sign the image by using the signing profile established previously, as shown in more detail in Figure 3.
    Figure 3: Signing images described

    Figure 3: Signing images described

  4. AWS Signer and Notation verify the signed image version and then deploy it to an Amazon EKS cluster.

    If the image has not previously been signed correctly, the CodeBuild log displays an output similar to the following:

    Error: signature verification failed: no signature is associated with "<AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/hello-server@<DIGEST>" , make sure the artifact was signed successfully

    If there is a signature mismatch, the CodeBuild log displays an output similar to the following:

    Error: signature verification failed for all the signatures associated with <AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/hello-server@<DIGEST>

  5. Kyverno verifies the container image signature for use in the Amazon EKS cluster.

    Figure 4 shows steps 4 and 5 in more detail.

    Figure 4: Verification of image signature for Kubernetes

    Figure 4: Verification of image signature for Kubernetes

Prerequisites

Before getting started, make sure that you have the following prerequisites in place:

  • An Amazon EKS cluster provisioned.
  • An Amazon ECR repository for your container images.
  • A CodeCommit repository with your application code. For more information, see Create an AWS CodeCommit repository.
  • A CodePipeline pipeline deployed with the CodeCommit repository as the code source and four CodeBuild stages: Build, ApplicationSigning, ApplicationDeployment, and VerifyContainerSign. The CI/CD pipeline should look like that in Figure 5.
    Figure 5: CI/CD pipeline with CodePipeline

    Figure 5: CI/CD pipeline with CodePipeline

Walkthrough

You can create a signing profile by using the AWS Command Line Interface (AWS CLI), AWS Management Console or the AWS Signer API. In this section, we’ll walk you through how to sign the image by using the AWS CLI.

To sign the image (AWS CLI)

  1. Create a signing profile for each identity.
    # Create an AWS Signer signing profile with default validity period
    $ aws signer put-signing-profile \
        --profile-name build_signer \
        --platform-id Notation-OCI-SHA384-ECDSA

  2. Sign the image from the CodeBuild build—your buildspec.yaml configuration file should look like the following:
    version: 0.2
    
    phases:
      pre_build:
        commands:
          - aws ecr get-login-password --region $AWS_REGION | docker login --username AWS --password-stdin $AWS_ACCOUNT_ID.dkr.ecr.us-east-1.amazonaws.com
          - REPOSITORY_URI=$AWS_ACCOUNT_ID.dkr.ecr. $AWS_REGION.amazonaws.com/hello-server
          - COMMIT_HASH=$(echo $CODEBUILD_RESOLVED_SOURCE_VERSION | cut -c 1-7)
          - IMAGE_TAG=${COMMIT_HASH:=latest}
          - DIGEST=$(docker manifest inspect $AWS_ACCOUNT_ID.dkr.ecr. $AWS_REGION.amazonaws.com/hello-server:$IMAGE_TAG -v | jq -r '.Descriptor.digest')
          - echo $DIGEST
          
          - wget https://d2hvyiie56hcat.cloudfront.net/linux/amd64/installer/rpm/latest/aws-signer-notation-cli_amd64.rpm
          - sudo rpm -U aws-signer-notation-cli_amd64.rpm
          - notation version
          - notation plugin ls
      build:
        commands:
          - notation sign $REPOSITORY_URI@$DIGEST --plugin com.amazonaws.signer.notation.plugin --id arn:aws:signer: $AWS_REGION:$AWS_ACCOUNT_ID:/signing-profiles/notation_container_signing
          - notation inspect $AWS_ACCOUNT_ID.dkr.ecr. $AWS_REGION.amazonaws.com/hello-server@$DIGEST
          - notation verify $AWS_ACCOUNT_ID.dkr.ecr. $AWS_REGION.amazonaws.com/hello-server@$DIGEST
      post_build:
        commands:
          - printf '[{"name":"hello-server","imageUri":"%s"}]' $REPOSITORY_URI:$IMAGE_TAG > imagedefinitions.json
    artifacts:
        files: imagedefinitions.json

    The commands in the buildspec.yaml configuration file do the following:

    1. Sign you in to Amazon ECR to work with the Docker images.
    2. Reference the specific image that will be signed by using the commit hash (or another versioning strategy that your organization uses). This gets the digest.
    3. Sign the container image by using the notation sign command. This command uses the container image digest, instead of the image tag.
    4. Install the Notation CLI. In this example, you use the installer for Linux. For a list of installers for various operating systems, see the AWS Signer Developer Guide,
    5. Sign the image by using the notation sign command.
    6. Inspect the signed image to make sure that it was signed successfully by using the notation inspect command.
    7. To verify the signed image, use the notation verify command. The output should look similar to the following:
      Successfully verified signature for <AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/hello-server@<DIGEST>

  3. (Optional) For troubleshooting, print the notation policy from the pipeline itself to check that it’s working as expected by running the notation policy show command:
    notation policy show

    For this, include the command in the pre_build phase after the notation version command in the buildspec.yaml configuration file.

    After the notation policy show command runs, CodeBuild logs should display an output similar to the following:

    {
      "version": "1.0",
      "trustPolicies": [
        {
          "name": "aws-signer-tp",
          "registryScopes": [
          "<AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/hello-server"
          ],
          "signatureVerification": {
            "level": "strict"
          },
          "trustStores": [
            "signingAuthority:aws-signer-ts"
          ],
          "trustedIdentities": [
            "arn:aws:signer:<AWS_REGION>:<AWS_ACCOUNT_ID>:/signing-profiles/notation_test"
          ]
        }
      ]
    }

  4. To verify the image in Kubernetes, set up both Kyverno and the Kyverno-notation-AWS Signer in your EKS cluster. To get started with Kyverno and the Kyverno-notation-AWS Signer solution, see the installation instructions.
  5. After you install Kyverno and Kyverno-notation-AWS Signer, verify that the controller is running—the STATUS should show Running:
    $ kubectl get pods -n kyverno-notation-aws -w
    
    NAME                                    READY   STATUS    RESTARTS   AGE
    kyverno-notation-aws-75b7ddbcfc-kxwjh   1/1     Running   0          6h58m

  6. Configure the CodeBuild buildspec.yaml configuration file to verify that the images deployed in the cluster have been previously signed. You can use the following code to configure the buildspec.yaml file.
    version: 0.2
    
    phases:
      pre_build:
        commands:
          - echo Logging in to Amazon ECR...
          - aws --version
          - REPOSITORY_URI=${REPO_ECR}
          - COMMIT_HASH=$(echo $CODEBUILD_RESOLVED_SOURCE_VERSION | cut -c 1-7)
          - IMAGE_TAG=${COMMIT_HASH:=latest}
          - curl -LO "https://dl.k8s.io/release/$(curl -L -s https://dl.k8s.io/release/stable.txt)/bin/linux/amd64/kubectl"
          - curl -LO "https://dl.k8s.io/release/$(curl -L -s https://dl.k8s.io/release/stable.txt)/bin/linux/amd64/kubectl.sha256"
          - echo "$(cat kubectl.sha256)  kubectl" | sha256sum --check
          — chmod +x kubectl
          - mv ./kubectl /usr/local/bin/kubectl
          - kubectl version --client
      build:
        commands:
          - echo Build started on `date`
          - aws eks update-kubeconfig -—name ${EKS_NAME} —-region ${AWS_DEFAULT_REGION}
          - echo Deploying Application
          - sed -i '/image:\ image/image:\ '\"${REPOSITORY_URI}:${IMAGE_TAG}\"'/g' deployment.yaml
          - kubectl apply -f deployment.yaml 
          - KYVERNO_NOTATION_POD=$(kubectl get pods --no-headers -o custom-columns=":metadata.name" -n kyverno-notation-aws)
          - STATUS=$(kubectl logs --tail=1 kyverno-notation-aws-75b7ddbcfc-kxwjh -n kyverno-notation-aws | grep $IMAGE_TAG | grep ERROR)
          - |
            if [[ $STATUS ]]; then
              echo "There is an error"
              exit 1
            else
              echo "No Error"
            fi
      post_build:
        commands:
          - printf '[{"name":"hello-server","imageUri":"%s"}]' $REPOSITORY_URI:$IMAGE_TAG > imagedefinitions.json
    artifacts:
        files: imagedefinitions.json

    The commands in the buildspec.yaml configuration file do the following:

    1. Set up the environment variables, such as the ECR repository URI and the Commit hash, to build the image tag. The kubectl tool will use this later to reference the container image that will be deployed with the Kubernetes objects.
    2. Use kubectl to connect to the EKS cluster and insert the container image reference in the deployment.yaml file.
    3. After the container is deployed, you can observe the kyverno-notation-aws controller and access its logs. You can check if the deployed image is signed. If the logs contain an error, stop the pipeline run with an error code, do a rollback to a previous version, or delete the deployment if you detect that the image isn’t signed.

Decommission the AWS resources

If you no longer need the resources that you provisioned for this post, complete the following steps to delete them.

To clean up the resources

  1. Delete the EKS cluster and delete the ECR image.
  2. Delete the IAM roles and policies that you used for the configuration of IAM roles for service accounts.
  3. Revoke the AWS Signer signing profile that you created and used for the signing process by running the following command in the AWS CLI:
    $ aws signer revoke-signing-profile

  4. Delete signatures from the Amazon ECR repository. Make sure to replace <AWS_ACCOUNT_ID> and <AWS_REGION> with your own information.
    # Use oras CLI, with Amazon ECR Docker Credential Helper, to delete signature
    $ oras manifest delete <AWS_ACCOUNT_ID>.dkr.ecr.<AWS_REGION>.amazonaws.com/pause@sha256:ca78e5f730f9a789ef8c63bb55275ac12dfb9e8099e6a0a64375d8a95ed501c4

Note: Using the ORAS project’s oras client, you can delete signatures and other reference type artifacts. It implements deletion by first removing the reference from an index, and then deleting the manifest.

Conclusion

In this post, you learned how to implement container image signing in a CI/CD pipeline by using AWS services such as CodePipeline, CodeBuild, Amazon ECR, and AWS Signer along with publicly available tools such as Notary and Kyverno. By implementing mandatory image signing in your pipelines, you can confirm that only validated and authorized container images are deployed to production. Automating the signing process and signature verification is vital to help securely deploy containers at scale. You also learned how to verify signed images both during deployment and at runtime in Kubernetes. This post provides valuable insights for anyone looking to add image signing capabilities to their CI/CD pipelines on AWS to provide supply chain security assurances. The combination of AWS managed services and publicly available tools provides a robust implementation.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Jorge Castillo

Jorge Castillo

Jorge is a Solutions Architect at AWS for the public sector based in Santiago, Chile. He focuses on security and compliance and works with many government agencies.

Joseph Rodríguez

Joseph Rodríguez

Joseph is a Solutions Architect at AWS for the public sector based in Chile. Joseph has collaborated with multiple public sector institutions on cloud technology adoption, with a focus on containers. He previously worked as a Software Architect at financial services institutions.

Monika Vu Minh

Monika Vu Minh

Monika is a ProServe Security Consultant at AWS based in London. She works with financial services customers to help them follow security best practices on AWS. In her free time, she likes painting, cooking, and travelling.

Accelerate analytics on Amazon OpenSearch Service with AWS Glue through its native connector

Post Syndicated from Basheer Sheriff original https://aws.amazon.com/blogs/big-data/accelerate-analytics-on-amazon-opensearch-service-with-aws-glue-through-its-native-connector/

As the volume and complexity of analytics workloads continue to grow, customers are looking for more efficient and cost-effective ways to ingest and analyse data. Data is stored from online systems such as the databases, CRMs, and marketing systems to data stores such as data lakes on Amazon Simple Storage Service (Amazon S3), data warehouses in Amazon Redshift, and purpose-built stores such as Amazon OpenSearch Service, Amazon Neptune, and Amazon Timestream.

OpenSearch Service is used for multiple purposes, such as observability, search analytics, consolidation, cost savings, compliance, and integration. OpenSearch Service also has vector database capabilities that let you implement semantic search and Retrieval Augmented Generation (RAG) with large language models (LLMs) to build recommendation and media search engines. Previously, to integrate with OpenSearch Service, you could use open source clients for specific programming languages such as Java, Python, or JavaScript or use REST APIs provided by OpenSearch Service.

Movement of data across data lakes, data warehouses, and purpose-built stores is achieved by extract, transform, and load (ETL) processes using data integration services such as AWS Glue. AWS Glue is a serverless data integration service that makes it straightforward to discover, prepare, and combine data for analytics, machine learning (ML), and application development. AWS Glue provides both visual and code-based interfaces to make data integration effortless. Using a native AWS Glue connector increases agility, simplifies data movement, and improves data quality.

In this post, we explore the AWS Glue native connector to OpenSearch Service and discover how it eliminates the need to build and maintain custom code or third-party tools to integrate with OpenSearch Service. This accelerates analytics pipelines and search use cases, providing instant access to your data in OpenSearch Service. You can now use data stored in OpenSearch Service indexes as a source or target within the AWS Glue Studio no-code, drag-and-drop visual interface or directly in an AWS Glue ETL job script. When combined with AWS Glue ETL capabilities, this new connector simplifies the creation of ETL pipelines, enabling ETL developers to save time building and maintaining data pipelines.

Solution overview

The new native OpenSearch Service connector is a powerful tool that can help organizations unlock the full potential of their data. It enables you to efficiently read and write data from OpenSearch Service without needing to install or manage OpenSearch Service connector libraries.

In this post, we demonstrate exporting the New York City Taxi and Limousine Commission (TLC) Trip Record Data dataset into OpenSearch Service using the AWS Glue native connector. The following diagram illustrates the solution architecture.

By the end of this post, your visual ETL job will resemble the following screenshot.

Prerequisites

To follow along with this post, you need a running OpenSearch Service domain. For setup instructions, refer to Getting started with Amazon OpenSearch Service. Ensure it is public, for simplicity, and note the primary user and password for later use.

Note that as of this writing, the AWS Glue OpenSearch Service connector doesn’t support Amazon OpenSearch Serverless, so you need to set up a provisioned domain.

Create an S3 bucket

We use an AWS CloudFormation template to create an S3 bucket to store the sample data. Complete the following steps:

  1. Choose Launch Stack.
  2. On the Specify stack details page, enter a name for the stack.
  3. Choose Next.
  4. On the Configure stack options page, choose Next.
  5. On the Review page, select I acknowledge that AWS CloudFormation might create IAM resources.
  6. Choose Submit.

The stack takes about 2 minutes to deploy.

Create an index in the OpenSearch Service domain

To create an index in the OpenSearch service domain, complete the following steps:

  1. On the OpenSearch Service console, choose Domains in the navigation pane.
  2. Open the domain you created as a prerequisite.
  3. Choose the link under OpenSearch Dashboards URL.
  4. On the navigation menu, choose Dev Tools.
  5. Enter the following code to create the index:
PUT /yellow-taxi-index
{
  "mappings": {
    "properties": {
      "VendorID": {
        "type": "integer"
      },
      "tpep_pickup_datetime": {
        "type": "date",
        "format": "epoch_millis"
      },
      "tpep_dropoff_datetime": {
        "type": "date",
        "format": "epoch_millis"
      },
      "passenger_count": {
        "type": "integer"
      },
      "trip_distance": {
        "type": "float"
      },
      "RatecodeID": {
        "type": "integer"
      },
      "store_and_fwd_flag": {
        "type": "keyword"
      },
      "PULocationID": {
        "type": "integer"
      },
      "DOLocationID": {
        "type": "integer"
      },
      "payment_type": {
        "type": "integer"
      },
      "fare_amount": {
        "type": "float"
      },
      "extra": {
        "type": "float"
      },
      "mta_tax": {
        "type": "float"
      },
      "tip_amount": {
        "type": "float"
      },
      "tolls_amount": {
        "type": "float"
      },
      "improvement_surcharge": {
        "type": "float"
      },
      "total_amount": {
        "type": "float"
      },
      "congestion_surcharge": {
        "type": "float"
      },
      "airport_fee": {
        "type": "integer"
      }
    }
  }
}

Create a secret for OpenSearch Service credentials

In this post, we use basic authentication and store our authentication credentials securely using AWS Secrets Manager. Complete the following steps to create a Secrets Manager secret:

  1. On the Secrets Manager console, choose Secrets in the navigation pane.
  2. Choose Store a new secret.
  3. For Secret type, select Other type of secret.
  4. For Key/value pairs, enter the user name opensearch.net.http.auth.user and the password opensearch.net.http.auth.pass.
  5. Choose Next.
  6. Complete the remaining steps to create your secret.

Create an IAM role for the AWS Glue job

Complete the following steps to configure an AWS Identity and Access Management (IAM) role for the AWS Glue job:

  1. On the IAM console, create a new role.
  2. Attach the AWS managed policy GlueServiceRole.
  3. Attach the following policy to the role. Replace each ARN with the corresponding ARN of the OpenSearch Service domain, Secrets Manager secret, and S3 bucket.
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "OpenSearchPolicy",
            "Effect": "Allow",
            "Action": [
                "es:ESHttpPost",
                "es:ESHttpPut"
            ],
            "Resource": [
                "arn:aws:es:<region>:<aws-account-id>:domain/<amazon-opensearch-domain-name>"
            ]
        },
        {
            "Sid": "GetDescribeSecret",
            "Effect": "Allow",
            "Action": [
                "secretsmanager:GetResourcePolicy",
                "secretsmanager:GetSecretValue",
                "secretsmanager:DescribeSecret",
                "secretsmanager:ListSecretVersionIds"
            ],
            "Resource": "arn:aws:secretsmanager:<region>:<aws-account-id>:secret:<secret-name>"
        },
        {
            "Sid": "S3Policy",
            "Effect": "Allow",
            "Action": [
                "s3:GetBucketLocation",
                "s3:ListBucket",
                "s3:GetBucketAcl",
                "s3:GetObject",
                "s3:PutObject",
                "s3:DeleteObject"
            ],
            "Resource": [
                "arn:aws:s3:::<bucket-name>",
                "arn:aws:s3:::<bucket-name>/*"
            ]
        }
    ]
}

Create an AWS Glue connection

Before you can use the OpenSearch Service connector, you need to create an AWS Glue connection for connecting to OpenSearch Service. Complete the following steps:

  1. On the AWS Glue console, choose Connections in the navigation pane.
  2. Choose Create connection.
  3. For Name, enter opensearch-connection.
  4. For Connection type, choose Amazon OpenSearch.
  5. For Domain endpoint, enter the domain endpoint of OpenSearch Service.
  6. For Port, enter HTTPS port 443.
  7. For Resource, enter yellow-taxi-index.

In this context, resource means the index of OpenSearch Service where the data is read from or written to.

  1. Select Wan only enabled.
  2. For AWS Secret, choose the secret you created earlier.
  3. Optionally, if you’re connecting to an OpenSearch Service domain in a VPC, specify a VPC, subnet, and security group to run AWS Glue jobs inside the VPC. For security groups, a self-referencing inbound rule is required. For more information, see Setting up networking for development for AWS Glue.
  4. Choose Create connection.

Create an ETL job using AWS Glue Studio

Complete the following steps to create your AWS Glue ETL job:

  1. On the AWS Glue console, choose Visual ETL in the navigation pane.
  2. Choose Create job and Visual ETL.
  3. On the AWS Glue Studio console, change the job name to opensearch-etl.
  4. Choose Amazon S3 for the data source and Amazon OpenSearch for the data target.

Between the source and target, you can optionally insert transform nodes. In this solution, we create a job that has only source and target nodes for simplicity.

  1. In the Data source properties section, specify the S3 bucket where the sample data is located, and choose Parquet as the data format.
  2. In the Data sink properties section, specify the connection you created in the previous section (opensearch-connection).
  3. Choose the Job details tab, and in the Basic properties section, specify the IAM role you created earlier.
  4. Choose Save to save your job, and choose Run to run the job.
  5. Navigate to the Runs tab to check the status of the job. When it is successful, the run status should be Succeeded.
  6. After the job runs successfully, navigate to OpenSearch Dashboards, and log in to the dashboard.
  7. Choose Dashboards Management on the navigation menu.
  8. Choose Index patterns, and choose Create index pattern.
  9. Enter yellow-taxi-index for Index pattern name.
  10. Choose tpep_pickup_datetime for Time.
  11. Choose Create index pattern. This index pattern will be used to visualize the index.
  12. Choose Discover on the navigation menu, and choose yellow-taxi-index.


You have now created an index in OpenSearch Service and loaded data into it from Amazon S3 in just a few steps using the AWS Glue OpenSearch Service native connector.

Clean up

To avoid incurring charges, clean up the resources in your AWS account by completing the following steps:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. From the list of jobs, select the job opensearch-etl, and on the Actions menu, choose Delete.
  3. On the AWS Glue console, choose Data connections in the navigation pane.
  4. Select opensearch-connection from the list of connectors, and on the Actions menu, choose Delete.
  5. On the IAM console, choose Roles in the navigation page.
  6. Select the role you created for the AWS Glue job and delete it.
  7. On the CloudFormation console, choose Stacks in the navigation pane.
  8. Select the stack you created for the S3 bucket and sample data and delete it.
  9. On the Secrets Manager console, choose Secrets in the navigation pane.
  10. Select the secret you created, and on the Actions menu, choose Delete.
  11. Reduce the waiting period to 7 days and schedule the deletion.

Conclusion

The integration of AWS Glue with OpenSearch Service adds the powerful ability to perform data transformation when integrating with OpenSearch Service for analytics use cases. This enables organizations to streamline data integration and analytics with OpenSearch Service. The serverless nature of AWS Glue means no infrastructure management, and you pay only for the resources consumed while your jobs are running. As organizations increasingly rely on data for decision-making, this native Spark connector provides an efficient, cost-effective, and agile solution to swiftly meet data analytics needs.


About the authors

Basheer Sheriff is a Senior Solutions Architect at AWS. He loves to help customers solve interesting problems leveraging new technology. He is based in Melbourne, Australia, and likes to play sports such as football and cricket.

Shunsuke Goto is a Prototyping Engineer working at AWS. He works closely with customers to build their prototypes and also helps customers build analytics systems.

How to implement client certificate revocation list checks at scale with API Gateway

Post Syndicated from Arthur Mnev original https://aws.amazon.com/blogs/security/how-to-implement-client-certificate-revocation-list-checks-at-scale-with-api-gateway/

ityAs you design your Amazon API Gateway applications to rely on mutual certificate authentication (mTLS), you need to consider how your application will verify the revocation status of a client certificate. In your design, you should account for the performance and availability of your verification mechanism to make sure that your application endpoints perform reliably.

In this blog post, I demonstrate an architecture that will help you on your journey to implement custom revocation checks against your certificate revocation list (CRL) for API Gateway. You will also learn advanced Amazon Simple Storage Service (Amazon S3) and AWS Lambda techniques to achieve higher performance and scalability.

Choosing the right certificate verification method

One of your first considerations is whether to use a CRL or the Online Certificate Status Protocol (OCSP), if your certificate authority (CA) offers this option. For an in-depth analysis of these two options, see my earlier blog post, Choosing the right certificate revocation method in ACM Private CA. In that post, I demonstrated that OCSP is a good choice when your application can tolerate high latency or a failure for certificate verification due to TLS service-to-OCSP connectivity. When you rely on mutual TLS authentication in a high-rate transactional environment, increased latency or OCSP reachability failures may affect your application. We strongly recommend that you validate the revocation status of your mutual TLS certificates. Verifying your client certificate status against the CRL is the correct approach for certificate verification if you require reliability and lower, predictable latency. A potential exception to this approach is the use case of AWS Certificate Manager Private Certificate Authority (AWS Private CA) with an OCSP responder hosted on AWS CloudFront.

With an AWS Private CA OCSP responder hosted on CloudFront, you can reduce the risks of network and latency challenges by relying on communication between AWS native services. While this post focuses on the solution that targets CRLs originating from any CA, if you use AWS Private CA with an OCSP responder, you should consider generating an OCSP request in your Lambda authorizer.

Mutual authentication with API Gateway

API Gateway mutual TLS authentication (mTLS) requires you to define a root of trust that will contain your certificate authority public key. During the mutual TLS authentication process, API Gateway performs the undifferentiated heavy lifting by offloading the certificate authentication and negotiation process. During the authentication process, API Gateway validates that your certificate is trusted, has valid dates, and uses a supported algorithm. Additionally, you can refer to the API Gateway documentation and related blog post for details about the mutual TLS authentication process on API Gateway.

Implementing mTLS certificate verification for API Gateway

In the remainder of this blog post, I’ll describe the architecture for a scalable implementation of a client certificate verification mechanism against a CRL on your API Gateway.

The certificate CRL verification process presented here relies on a custom Lambda authorizer that validates the certificate revocation status against the CRL. The Lambda authorizer caches CRL data to optimize the query time for subsequent requests and allows you to define custom business logic that could go beyond CRL verification. For example, you could include other, just-in-time authorization decisions as a part of your evaluation logic.

Implementation mechanisms

This section describes the implementation mechanisms that help you create a high-performing extension to the API Gateway mutual TLS authentication process.

Data repository for your certificate revocation list

API Gateway mutual TLS configuration uses Amazon S3 as a repository for your root of trust. The design for this sample implementation extends the use of S3 buckets to store your CRL and the public key for the certificate authority that signed the CRL.

We strongly recommend that you maintain an updated CRL and verify its signature before data processing. This process is automatic if you use AWS Private CA, because AWS Private CA will update your CRL automatically on revocation. AWS Private CA also allows you to retrieve the CA’s public key by using an API call.

Certificate validation

My sample implementation architecture uses the API Gateway Lambda authorizer to validate the serial number of the client certificate used in the mutual TLS authentication session against the list of serial numbers present in the CRL you publish to the S3 bucket. In the process, the API Gateway custom authorizer will read the client certificate serial number, read and validate the CRL’s digital signature, search for the client’s certificate serial number within the CRL, and return the authorization policy based on the findings.

Optimizing for performance

The mechanisms that enable a predictable, low-latency performance are CRL preprocessing and caching. Your CRL is an ASN.1 data structure that requires a relatively high computing time for processing. Preprocessing your CRL into a simple-to-parse data structure reduces the computational cost you would otherwise incur for every validation; caching the CRL will help you reduce the validation latency and improve predictability further.

Performance optimizations

The process of parsing and validating CRLs is computationally expensive. In the case of large CRL files, parsing the CRL in the Lambda authorizer on every request can result in high latency and timeouts. To improve latency and reduce compute costs, this solution optimizes for performance by preprocessing the CRL and implementing function-level caching.

Preprocessing and generation of a cached CRL file

The first optimization happens when S3 receives a new CRL object. As shown in Figure 1, the S3 PutObject event invokes a preprocessing Lambda that validates the signature of your uploaded CRL and decodes its ASN.1 format. The output of the preprocessing Lambda function is the list of the revoked certificate serial numbers from the CRL, in a data structure that is simpler to read by your programming language of choice, and that won’t require extensive parsing by your Lambda authorizer. The asynchronous approach mitigates the impact of CRL processing on your API Gateway workload.

Figure 1: Sample implementation flow of the pre-processing component

Figure 1: Sample implementation flow of the pre-processing component

Client certificate lookup in a CRL

The optimization happens as part of your Lambda authorizer that retrieves the preprocessed CRL data generated from the first step and searches through the data structure for your client certificate serial number. If the Lambda authorizer finds your client’s certificate serial number in the CRL, the authorization request fails, and the Lambda authorizer generates a “Deny” policy. Searching through a read-optimized data structure prepared by your preprocessing step is the second optimization that reduces the lookup time and the compute requirements.

Function-level caching

Because of the preprocessing, the Lambda authorizer code no longer needs to perform the expensive operation of decoding the ASN.1 data structures of the original CRL; however, network transfer latency will remain and may impact your application.

To improve performance, and as a third optimization, the Lambda service retains the runtime environment for a recently-run function for a non-deterministic period of time. If the function is invoked again during this time period, the Lambda function doesn’t have to initialize and can start running immediately. This is called a warm start. Function-level caching takes advantage of this warm start to hold the CRL data structure in memory persistently between function invocations so the Lambda function doesn’t have to download the preprocessed CRL data structure from S3 on every request.

The duration of the Lambda container’s warm state depends on multiple factors, such as usage patterns and parallel requests processed by your function. If, in your case, API use is infrequent or its usage pattern is spiky, pre-provisioned concurrency is another technique that can further reduce your Lambda startup times and the duration of your warm cache. Although provisioned concurrency does have additional costs, I recommend you evaluate its benefits for your specific environment. You can also check out the blog dedicated to this topic, Scheduling AWS Lambda Provisioned Concurrency for recurring peak usage.

To validate that the Lambda authorizer has the latest copy of the CRL data structure, the S3 ETag value is used to determine if the object has changed. The preprocessed CRL object’s ETag value is stored as a Lambda global variable, so its value is retained between invocations in the same runtime environment. When API Gateway invokes the Lambda authorizer, the function checks for existing global preprocessed CRL data structure and ETag variables. The process will only retrieve a read-optimized CRL when the ETag is absent, or its value differs from the ETag of the preprocessed CRL object in S3.

Figure 2 demonstrates this process flow.

Figure 2: Sample implementation flow for the Lambda authorizer component

Figure 2: Sample implementation flow for the Lambda authorizer component

In summary, you will have a Lambda container with a persistent in-memory lookup data structure for your CRL by doing the following:

  • Asynchronously start your preprocessing workflow by using the S3 PutObject event so you can generate and store your preprocessed CRL data structure in a separate S3 object.
  • Read the preprocessed CRL from S3 and its ETag value and store both values in global variables.
  • Compare the value of the ETag stored in your global variables to the current ETag value of the preprocessed CRL S3 object, to reduce unnecessary downloads if the current ETag value of your S3 object is the same as the previous value.
  • We recommend that you avoid using built-in API Gateway Lambda authorizer result caching, because the status of your certificate might change, and your authorization decision would rest on out-of-date verification results.
  • Consider setting a reserved concurrency for your CRL verification function so that API Gateway can invoke your function even if the overall capacity for your account in your AWS Region is exhausted.

The sample implementation flow diagram in Figure 3 demonstrates the overall architecture of the solution.

Figure 3: Sample implementation flow for the overall CRL verification architecture

Figure 3: Sample implementation flow for the overall CRL verification architecture

The workflow for the solution overall is as follows:

  1. An administrator publishes a CRL and its signing CA’s certificate to their non-public S3 bucket, which is accessible by the Lambda authorizer and preprocessor roles.
  2. An S3 event invokes the Lambda preprocessor to run upon CRL upload. The function retrieves the CRL from S3, validates its signature against the issuing certificate, and parses the CRL.
  3. The preprocessor Lambda stores the results in an S3 bucket with a name in the form <crlname>.cache.json.
  4. A TLS client requests an mTLS connection and supplies its certificate.
  5. API Gateway completes mTLS negotiation and invokes the Lambda authorizer.
  6. The Lambda authorizer function parses the client’s mTLS certificate, retrieves the cached CRL object, and searches the object for the serial number of the client’s certificate.
  7. The authorizer function returns a deny policy if the certificate is revoked or in error.
  8. API Gateway, if authorized, proceeds with the integrated function or denies the client’s request.

Conclusion

In this post, I presented a design for validating your API Gateway mutual TLS client certificates against a CRL, with support for extra-large certificate revocation files. This approach will help you align with the best security practices for validating client certificates and use advanced S3 access and Lambda caching techniques to minimize time and latency for validation.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, and Compliance re:Post or contact AWS Support.

Arthur Mnev

Arthur is a Senior Specialist Security Architect for AWS Industries. He spends his day working with customers and designing innovative approaches to help customers move forward with their initiatives, improve their security posture, and reduce security risks in their cloud journeys. Outside of work, Arthur enjoys being a father, skiing, scuba diving, and Krav Maga.

Rafael Cassolato de Meneses

Rafael Cassolato de Meneses

Rafael Cassolato is a Solutions Architect with 20+ years in IT, holding bachelor’s and master’s degrees in Computer Science and 10 AWS certifications. Specializing in migration and modernization, Rafael helps strategic AWS customers achieve their business goals and solve technical challenges by leveraging AWS’s cloud platform.

Build efficient ETL pipelines with AWS Step Functions distributed map and redrive feature

Post Syndicated from Sriharsh Adari original https://aws.amazon.com/blogs/big-data/build-efficient-etl-pipelines-with-aws-step-functions-distributed-map-and-redrive-feature/

AWS Step Functions is a fully managed visual workflow service that enables you to build complex data processing pipelines involving a diverse set of extract, transform, and load (ETL) technologies such as AWS Glue, Amazon EMR, and Amazon Redshift. You can visually build the workflow by wiring individual data pipeline tasks and configuring payloads, retries, and error handling with minimal code.

While Step Functions supports automatic retries and error handling when data pipeline tasks fail due to momentary or transient errors, there can be permanent failures such as incorrect permissions, invalid data, and business logic failure during the pipeline run. This requires you to identify the issue in the step, fix the issue and restart the workflow. Previously, to rerun the failed step, you needed to restart the entire workflow from the very beginning. This leads to delays in completing the workflow, especially if it’s a complex, long-running ETL pipeline. If the pipeline has many steps using map and parallel states, this also leads to increased cost due to increases in the state transition for running the pipeline from the beginning.

Step Functions now supports the ability for you to redrive your workflow from a failed, aborted, or timed-out state so you can complete workflows faster and at a lower cost, and spend more time delivering business value. Now you can recover from unhandled failures faster by redriving failed workflow runs, after downstream issues are resolved, using the same input provided to the failed state.

In this post, we show you an ETL pipeline job that exports data from Amazon Relational Database Service (Amazon RDS) tables using the Step Functions distributed map state. Then we simulate a failure and demonstrate how to use the new redrive feature to restart the failed task from the point of failure.

Solution overview

One of the common functionalities involved in data pipelines is extracting data from multiple data sources and exporting it to a data lake or synchronizing the data to another database. You can use the Step Functions distributed map state to run hundreds of such export or synchronization jobs in parallel. Distributed map can read millions of objects from Amazon Simple Storage Service (Amazon S3) or millions of records from a single S3 object, and distribute the records to downstream steps. Step Functions runs the steps within the distributed map as child workflows at a maximum parallelism of 10,000. A concurrency of 10,000 is well above the concurrency supported by many other AWS services such as AWS Glue, which has a soft limit of 1,000 job runs per job.

The sample data pipeline sources product catalog data from Amazon DynamoDB and customer order data from Amazon RDS for PostgreSQL database. The data is then cleansed, transformed, and uploaded to Amazon S3 for further processing. The data pipeline starts with an AWS Glue crawler to create the Data Catalog for the RDS database. Because starting an AWS Glue crawler is asynchronous, the pipeline has a wait loop to check if the crawler is complete. After the AWS Glue crawler is complete, the pipeline extracts data from the DynamoDB table and RDS tables. Because these two steps are independent, they are run as parallel steps: one using an AWS Lambda function to export, transform, and load the data from DynamoDB to an S3 bucket, and the other using a distributed map with AWS Glue job sync integration to do the same from the RDS tables to an S3 bucket. Note that AWS Identity and Access Management (IAM) permissions are required for invoking an AWS Glue job from Step Functions. For more information, refer to IAM Policies for invoking AWS Glue job from Step Functions.

The following diagram illustrates the Step Functions workflow.

There are multiple tables related to customers and order data in the RDS database. Amazon S3 hosts the metadata of all the tables as a .csv file. The pipeline uses the Step Functions distributed map to read the table metadata from Amazon S3, iterate on every single item, and call the downstream AWS Glue job in parallel to export the data. See the following code:

"States": {
            "Map": {
              "Type": "Map",
              "ItemProcessor": {
                "ProcessorConfig": {
                  "Mode": "DISTRIBUTED",
                  "ExecutionType": "STANDARD"
                },
                "StartAt": "Export data for a table",
                "States": {
                  "Export data for a table": {
                    "Type": "Task",
                    "Resource": "arn:aws:states:::glue:startJobRun.sync",
                    "Parameters": {
                      "JobName": "ExportTableData",
                      "Arguments": {
                        "--dbtable.$": "$.tables"
                      }
                    },
                    "End": true
                  }
                }
              },
              "Label": "Map",
              "ItemReader": {
                "Resource": "arn:aws:states:::s3:getObject",
                "ReaderConfig": {
                  "InputType": "CSV",
                  "CSVHeaderLocation": "FIRST_ROW"
                },
                "Parameters": {
                  "Bucket": "123456789012-stepfunction-redrive",
                  "Key": "tables.csv"
                }
              },
              "ResultPath": null,
              "End": true
            }
          }

Prerequisites

To deploy the solution, you need the following prerequisites:

Launch the CloudFormation template

Complete the following steps to deploy the solution resources using AWS CloudFormation:

  1. Choose Launch Stack to launch the CloudFormation stack:
  2. Enter a stack name.
  3. Select all the check boxes under Capabilities and transforms.
  4. Choose Create stack.

The CloudFormation template creates many resources, including the following:

  • The data pipeline described earlier as a Step Functions workflow
  • An S3 bucket to store the exported data and the metadata of the tables in Amazon RDS
  • A product catalog table in DynamoDB
  • An RDS for PostgreSQL database instance with pre-loaded tables
  • An AWS Glue crawler that crawls the RDS table and creates an AWS Glue Data Catalog
  • A parameterized AWS Glue job to export data from the RDS table to an S3 bucket
  • A Lambda function to export data from DynamoDB to an S3 bucket

Simulate the failure

Complete the following steps to test the solution:

  1. On the Step Functions console, choose State machines in the navigation pane.
  2. Choose the workflow named ETL_Process.
  3. Run the workflow with default input.

Within a few seconds, the workflow fails at the distributed map state.

You can inspect the map run errors by accessing the Step Functions workflow execution events for map runs and child workflows. In this example, you can identity the exception is due to Glue.ConcurrentRunsExceededException from AWS Glue. The error indicates there are more concurrent requests to run an AWS Glue job than are configured. Distributed map reads the table metadata from Amazon S3 and invokes as many AWS Glue jobs as the number of rows in the .csv file, but AWS Glue job is set with the concurrency of 3 when it is created. This resulted in the child workflow failure, cascading the failure to the distributed map state and then the parallel state. The other step in the parallel state to fetch the DynamoDB table ran successfully. If any step in the parallel state fails, the whole state fails, as seen with the cascading failure.

Handle failures with distributed map

By default, when a state reports an error, Step Functions causes the workflow to fail. There are multiple ways you can handle this failure with distributed map state:

  • Step Functions enables you to catch errors, retry errors, and fail back to another state to handle errors gracefully. See the following code:
    Retry": [
                          {
                            "ErrorEquals": [
                              "Glue.ConcurrentRunsExceededException "
                            ],
                            "BackoffRate": 20,
                            "IntervalSeconds": 10,
                            "MaxAttempts": 3,
                            "Comment": "Exception",
                            "JitterStrategy": "FULL"
                          }
                        ]
    

  • Sometimes, businesses can tolerate failures. This is especially true when you are processing millions of items and you expect data quality issues in the dataset. By default, when an iteration of map state fails, all other iterations are aborted. With distributed map, you can specify the maximum number of, or percentage of, failed items as a failure threshold. If the failure is within the tolerable level, the distributed map doesn’t fail.
  • The distributed map state allows you to control the concurrency of the child workflows. You can set the concurrency to map it to the AWS Glue job concurrency. Remember, this concurrency is applicable only at the workflow execution level—not across workflow executions.
  • You can redrive the failed state from the point of failure after fixing the root cause of the error.

Redrive the failed state

The root cause of the issue in the sample solution is the AWS Glue job concurrency. To address this by redriving the failed state, complete the following steps:

  1. On the AWS Glue console, navigate to the job named ExportsTableData.
  2. On the Job details tab, under Advanced properties, update Maximum concurrency to 5.

With the launch of redrive feature, You can use redrive to restart executions of standard workflows that didn’t complete successfully in the last 14 days. These include failed, aborted, or timed-out runs. You can only redrive a failed workflow from the step where it failed using the same input as the last non-successful state. You can’t redrive a failed workflow using a state machine definition that is different from the initial workflow execution. After the failed state is redriven successfully, Step Functions runs all the downstream tasks automatically. To learn more about how distributed map redrive works, refer to Redriving Map Runs.

Because the distributed map runs the steps inside the map as child workflows, the workflow IAM execution role needs permission to redrive the map run to restart the distributed map state:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "states:RedriveExecution"
      ],
      "Resource": "arn:aws:states:us-east-2:123456789012:execution:myStateMachine/myMapRunLabel:*"
    }
  ]
}

You can redrive a workflow from its failed step programmatically, via the AWS Command Line Interface (AWS CLI) or AWS SDK, or using the Step Functions console, which provides a visual operator experience.

  1. On the Step Functions console, navigate to the failed workflow you want to redrive.
  2. On the Details tab, choose Redrive from failure.

The pipeline now runs successfully because there is enough concurrency to run the AWS Glue jobs.

To redrive a workflow programmatically from its point of failure, call the new Redrive Execution API action. The same workflow starts from the last non-successful state and uses the same input as the last non-successful state from the initial failed workflow. The state to redrive from the workflow definition and the previous input are immutable.

Note the following regarding different types of child workflows:

  • Redrive for express child workflows – For failed child workflows that are express workflows within a distributed map, the redrive capability ensures a seamless restart from the beginning of the child workflow. This allows you to resolve issues that are specific to individual iterations without restarting the entire map.
  • Redrive for standard child workflows – For failed child workflows within a distributed map that are standard workflows, the redrive feature functions the same way as with standalone standard workflows. You can restart the failed state within each map iteration from its point of failure, skipping unnecessary steps that have already successfully run.

You can use Step Functions status change notifications with Amazon EventBridge for failure notifications such as sending an email on failure.

Clean up

To clean up your resources, delete the CloudFormation stack via the AWS CloudFormation console.

Conclusion

In this post, we showed you how to use the Step Functions redrive feature to redrive a failed step within a distributed map by restarting the failed step from the point of failure. The distributed map state allows you to write workflows that coordinate large-scale parallel workloads within your serverless applications. Step Functions runs the steps within the distributed map as child workflows at a maximum parallelism of 10,000, which is well above the concurrency supported by many AWS services.

To learn more about distributed map, refer to Step Functions – Distributed Map. To learn more about redriving workflows, refer to Redriving executions.


About the Authors

Sriharsh Adari is a Senior Solutions Architect at Amazon Web Services (AWS), where he helps customers work backwards from business outcomes to develop innovative solutions on AWS. Over the years, he has helped multiple customers on data platform transformations across industry verticals. His core area of expertise include Technology Strategy, Data Analytics, and Data Science. In his spare time, he enjoys playing Tennis.

Joe Morotti is a Senior Solutions Architect at Amazon Web Services (AWS), working with Enterprise customers across the Midwest US to develop innovative solutions on AWS. He has held a wide range of technical roles and enjoys showing customers the art of the possible. He has attained seven AWS certification and has a passion for AI/ML and the contact center space. In his free time, he enjoys spending quality time with his family exploring new places and overanalyzing his sports team’s performance.

Uma Ramadoss is a specialist Solutions Architect at Amazon Web Services, focused on the Serverless platform. She is responsible for helping customers design and operate event-driven cloud-native applications and modern business workflows using services like Lambda, EventBridge, Step Functions, and Amazon MWAA.
Four use cases for GuardDuty Malware Protection On-demand malware scan

Post Syndicated from Eduardo Ortiz Pineda original https://aws.amazon.com/blogs/security/four-use-cases-for-guardduty-malware-protection-on-demand-malware-scan/

Amazon GuardDuty is a threat detection service that continuously monitors your Amazon Web Services (AWS) accounts and workloads for malicious activity and delivers detailed security findings for visibility and remediation. GuardDuty Malware Protection helps detect the presence of malware by performing agentless scans of the Amazon Elastic Block Store (Amazon EBS) volumes that are attached to Amazon Elastic Compute Cloud (Amazon EC2) instances and container workloads. GuardDuty findings for identified malware provide additional insights of potential threats related to EC2 instances and containers running on an instance. Malware findings can also provide additional context for EC2 related threats identified by GuardDuty such as observed cryptocurrency-related activity and communication with a command and control server. Examples of malware categories that GuardDuty Malware Protection helps identify include ransomware, cryptocurrency mining, remote access, credential theft, and phishing. In this blog post, we provide an overview of the On-demand malware scan feature in GuardDuty and walk through several use cases where you can use On-demand malware scanning.

GuardDuty offers two types of malware scanning for EC2 instances: GuardDuty-initiated malware scans and On-demand malware scans. GuardDuty initiated malware scans are launched after GuardDuty generates an EC2 finding that indicates behavior typical of malware on an EC2 instance or container workload. The initial EC2 finding helps to provide insight that a specific threat is being observed based on VPC Flow Logs and DNS logs. Performing a malware scan on the instance goes beyond what can be observed from log activity and helps to provide additional context at the instance file system level, showing a connection between malware and the observed network traffic. This additional context can also help you determine your response and remediation steps for the identified threat.

There are multiple use cases where you would want to scan an EC2 instance for malware even when there’s no GuardDuty EC2 finding for the instance. This could include scanning as part of a security investigation or scanning certain instances on a regular schedule. You can use the On-demand malware scan feature to scan an EC2 instance when you want, providing flexibility in how you maintain the security posture of your EC2 instances.

On-demand malware scanning

To perform on-demand malware scanning, your account must have GuardDuty enabled. If the service-linked role (SLR) permissions for Malware Protection don’t exist in the account the first time that you submit an on-demand scan, the SLR for Malware Protection will automatically be created. An on-demand malware scan is initiated by providing the Amazon Resource Name (ARN) of the EC2 instance to scan. The malware scan of the instance is performed using the same functionality as GuardDuty-initiated scans. The malware scans that GuardDuty performs are agentless and the feature is designed in a way that it won’t affect the performance of your resources.

An on-demand malware scan can be initiated through the GuardDuty Malware Protection section of the AWS Management Console for GuardDuty or through the StartMalwareScan API. On-demand malware scans can be initiated from the GuardDuty delegated administrator account for EC2 instances in a member account where GuardDuty is enabled, or the scan can be initiated from a member account or a stand-alone account for Amazon EC2 instances within that account. High-level details for every malware scan that GuardDuty runs are reported in the Malware scans section of the GuardDuty console. The Malware scans section identifies which EC2 instance the scan was initiated for, the status of the scan (completed, running, skipped, or failed), the result of the scan (clean or infected), and when the malware scan was initiated. This summary information on malware scans is also available through the DescribeMalwareScans API.

When an on-demand scan detects malware on an EC2 instance, a new GuardDuty finding is created. This finding lists the details about the impacted EC2 instance, where malware was found in the instance file system, how many occurrences of malware were found, and details about the actual malware. Additionally, if malware was found in a Docker container, the finding also lists details about the container and, if the EC2 instance is used to support Amazon Elastic Kubernetes Service (Amazon EKS) or Amazon Elastic Container Service (Amazon ECS) container deployments, details about the cluster, task, and pod are also included in the finding. Findings about identified malware can be viewed in the GuardDuty console along with other GuardDuty findings or can be retrieved using the GuardDuty APIs. Additionally, each finding that GuardDuty generates is sent to Amazon EventBridge and AWS Security Hub. With EventBridge, you can author rules that allow you to match certain GuardDuty findings and then send the findings to a defined target in an event-driven flow. Security Hub helps you include GuardDuty findings in your aggregation and prioritization of security findings for your overall AWS environment.

GuardDuty charges for the total amount of Amazon EBS data that’s scanned. You can use the provisioned storage for an Amazon EBS volume to get an initial estimate on what the scan will cost. When the actual malware scan runs, the final cost is based on the amount of data that was actually scanned by GuardDuty to perform a malware scan. To get a more accurate estimate of what a malware scan on an Amazon EBS volume might cost, you must obtain the actual storage amount used from the EC2 instance that the volume is attached to. There are multiple methods available to determine the actual amount of storage currently being used on an EBS volume including using the CloudWatch Logs agent to collect disk-used metrics, and running individual commands to see the amount of free disk space on Linux and Windows EC2 instances.

Use cases using GuardDuty On-demand malware scan

Now that you’ve reviewed the on-demand malware scan feature and how it works, let’s walk through four use cases where you can incorporate it to help you achieve your security goals. In use cases 1 and 2, we provide you with deployable assets to help demonstrate the solution in your own environment.

Use case 1 – Initiating scans for EC2 instances with specific tags

This first use case walks through how on-demand scanning can be performed based on tags applied to an EC2 instance. Each tag is a label consisting of a key and an optional value to store information about the resource or data retained on that resource. Resource tagging can be used to help identify a specific target group of EC2 instances for malware scanning to meet your security requirements. Depending on your organization’s strategy, tags can indicate the data classification strategy, workload type, or the compliance scope of your EC2 instance, which can be used as criteria for malware scanning.

In this solution, you use a combination of GuardDuty, an AWS Systems Manager document (SSM document), Amazon CloudWatch Logs subscription filters, AWS Lambda, and Amazon Simple Notification Service (Amazon SNS) to initiate a malware scan of EC2 instances containing a specific tag. This solution is designed to be deployed in a member account and identifies EC2 instances to scan within that member account.

Solution architecture

Figure 1 shows the high-level architecture of the solution which depicts an on-demand malware scan being initiated based on a tag key.

Figure 1: Tag based on-demand malware scan architecture

Figure 1: Tag based on-demand malware scan architecture

The high-level workflow is:

  1. Enter the tag scan parameters in the SSM document that’s deployed as part of the solution.
  2. When you initiate the SSM document, the GuardDutyMalwareOnDemandScanLambdaFunction Lambda function is invoked, which launches the collection of the associated Amazon EC2 ARNs that match your tag criteria.
  3. The Lambda function obtains ARNs of the EC2 instances and initiates a malware scan for each instance.
  4. GuardDuty scans each instance for malware.
  5. A CloudWatch Logs subscription filter created under the log group /aws/guardduty/malware-scan-events monitors for log file entries of on-demand malware scans which have a status of COMPLETED or SKIPPED. If a scan matches this filter criteria, it’s sent to the GuardDutyMalwareOnDemandNotificationLambda Lambda function.
  6. The GuardDutyMalwareOnDemandNotificationLambda function parses the information from the scan events and sends the details to an Amazon SNS topic if the result of the scan is clean, skipped, or infected.
  7. Amazon SNS sends the message to the topic subscriptions. Information sent in the message will contain the account ID, resource ID, status, volume, and result of the scan.

Systems Manager document

AWS Systems Manager is a secure, end-to-end management solution for resources on AWS and in multi-cloud and hybrid environments. The SSM document feature is used in this solution to provide an interactive way to provide inputs to the Lambda function that’s responsible for identifying EC2 instances to scan for malware.

Identify Amazon EC2 targets Lambda

The GuardDutyMalwareOnDemandScanLambdaFunction obtains the ARN of the associated EC2 instances that match the tag criteria provided in the Systems Manager document parameters. For the EC2 instances that are identified to match the tag criteria, an On-demand malware scan request is submitted by the StartMalwareScan API.

Monitoring and reporting scan status

The solution deploys an Amazon CloudWatch Logs subscription filter that monitors for log file entries of on-demand malware scans which have a status of COMPLETED or SKIPPED. See Monitoring scan status for more information. After an on-demand malware scan finishes, the filter criteria are matched and the scan result is sent to its Lambda function destination GuardDutyMalwareOnDemandNotificationLambda. This Lambda function generates an Amazon SNS notification email that’s sent by the GuardDutyMalwareOnDemandScanTopic Amazon SNS topic.

Deploy the solution

Now that you understand how the on-demand malware scan solution works, you can deploy it to your own AWS account. The solution should be deployed in a single member account. This section walks you through the steps to deploy the solution and shows you how to verify that each of the key steps is working.

Step 1: Activate GuardDuty

The sample solution provided by this blog post requires that you activate GuardDuty in your AWS account. If this service isn’t activated in your account, learn more about the free trial and pricing or this service, and follow the steps in Getting started with Amazon GuardDuty to set up the service and start monitoring your account.

Note: On-demand malware scanning is not part of the GuardDuty free trial.

Step 2: Deploy the AWS CloudFormation template

For this step, deploy the template within the AWS account and AWS Region where you want to test this solution.

  1. Choose the following Launch Stack button to launch an AWS CloudFormation stack in your account. Use the AWS Management Console navigation bar to choose the Region you want to deploy the stack in.

    Launch Stack

  2. Set the values for the following parameters based on how you want to use the solution:
    • Create On-demand malware scan sample tester condition — Set the value to True to generate two EC2 instances to test the solution. These instances will serve as targets for an on-demand malware scan. One instance will contain EICAR malware sample files, which contain strings that will be detected as malware but aren’t malicious. The other instance won’t contain malware.
    • Tag key — Set the key that you want to be added to the test EC2 instances that are launched by this template.
    • Tag value — Set the value that will be added to the test EC2 instances that are launched by this template.
    • Latest Amazon Linux instance used for tester — Leave as is.
  3. Scroll to the bottom of the Quick create stack screen and select the checkbox next to I acknowledge that AWS CloudFormation might create IAM resources.
  4. Choose Create stack. The deployment of this CloudFormation stack will take 5–10 minutes.

After the CloudFormation stack has been deployed successfully, you can proceed to reviewing and interacting with the deployed solution.

Step 3: Create an Amazon SNS topic subscription

The CloudFormation stack deploys an Amazon SNS topic to support sending notifications about initiated malware scans. For this post, you create an email subscription for receiving messages sent through the topic.

  1. In the Amazon SNS console, navigate to the Region that the stack was deployed in. On the Amazon SNS topics page, choose the created topic that includes the text GuardDutyMalwareOnDemandScanTopic.
    Figure 2: Amazon SNS topic listing

    Figure 2: Amazon SNS topic listing

  2. On the Create subscription page, select Email for the Protocol, and for the Endpoint add a valid email address. Choose Create subscription.
    Figure 3: Amazon SNS topic subscription

    Figure 3: Amazon SNS topic subscription

After the subscription has been created, an email notification is sent that must be acknowledged to start receiving malware scan notifications.

Amazon SNS subscriptions support many other types of subscription protocols besides email. You can review the list of Amazon SNS event destinations to learn more about other ways that Amazon SNS notifications can be consumed.

Step 4: Provide scan parameters in an SSM document

After the AWS CloudFormation template has been deployed, the SSM document will be in the Systems Manager console. For this solution, the TagKey and TagValue parameters must be entered before you can run the SSM document.

  1. In the Systems Manager console choose the Documents link in the navigation pane.
  2. On the SSM document page, select the Owned by me tab and choose GuardDutyMalwareOnDemandScan. If you have multiple documents, use the search bar to search for the GuardDutyMalwareOnDemandScan document.
    Figure 4: Systems Manager documents listing

    Figure 4: Systems Manager documents listing

  3. In the page for the GuardDutyMalwareOnDemandScan, choose Execute automation.
  4. In the Execute automation runbook page, follow the document description and input the required parameters. For this blog example, use the same tags as in the parameter section of the initial CloudFormation template. When you use this solution for your own instances, you can adjust these parameters to fit your tagging strategy.
    Figure 5: Automation document details and input parameters

    Figure 5: Automation document details and input parameters

  5. Choose Execute to run the document. This takes you to the Execution detail page for this run of the automation document. In a few minutes the Execution status should update its overall status to Success.
    Figure 6: Automation document execution detail

    Figure 6: Automation document execution detail

Step 5: Receive status messages about malware scans

  1. Upon completion of the scan, you should get a status of Success and email containing the results of the on-demand scan along with the scan IDs. The scan result includes a message for an INFECTED instance and one message for a CLEAN instance. For EC2 instances without a tag key, you will receive an Amazon SNS notification that says “No instances found that could be scanned.” Figure 7 shows an example email for an INFECTED instance.
    Figure 7: Example email for an infected instance

    Figure 7: Example email for an infected instance

Step 6: Review scan results in GuardDuty

In addition to the emails that are sent about the status of a malware scan, the details about each malware scan and the findings for identified malware can be viewed in GuardDuty.

  1. In the GuardDuty console, select Malware scans from the left navigation pane. The Malware scan page provides you with the results of the scans performed. The scan results, for the instances scanned in this post, should match the email notifications received in the previous step.
    Figure 8: GuardDuty malware scan summary

    Figure 8: GuardDuty malware scan summary

  2. You can select a scan to view its details. The details include the scan ID, the EC2 instance, scan type, scan result (which indicates if the scan is infected or clean), and the scan start time.
    Figure 9: GuardDuty malware scan details

    Figure 9: GuardDuty malware scan details

  3. In the details for the infected instance, choose Click to see malware findings. This takes you to the GuardDuty findings page with a filter for the specific malware scan.
    Figure 10: GuardDuty malware findings

    Figure 10: GuardDuty malware findings

  4. Select the finding for the MalicousFile finding to bring up details about the finding. Details of the Execution:EC2/Malicious file finding include the severity label, the overview of the finding, and the threats detected. We recommend that you treat high severity findings as high priority and immediately investigate and, if necessary, take steps to prevent unauthorized use of your resources.
    Figure 11: GuardDuty malware finding details

    Figure 11: GuardDuty malware finding details

Use case 2 – Initiating scans on a schedule

This use case walks through how to schedule malware scans. Scheduled malware scanning might be required for particularly sensitive workloads. After an environment is up and running, it’s important to establish a baseline to be able to quickly identify EC2 instances that have been infected with malware. A scheduled malware scan helps you proactively identify malware on key resources and that maintain the desired security baseline.

Solution architecture

Figure 12: Scheduled malware scan architecture

Figure 12: Scheduled malware scan architecture

The architecture of this use case is shown in figure 12. The main difference between this and the architecture of use case 1 is the presence of a scheduler that controls submitting the GuardDutyMalwareOnDemandObtainScanLambdaFunction function to identify the EC2 instances to be scanned. This architecture uses Amazon EventBridge Scheduler to set up flexible time windows for when a scheduled scan should be performed.

EventBridge Scheduler is a serverless scheduler that you can use to create, run, and manage tasks from a central, managed service. With EventBridge Scheduler, you can create schedules using cron and rate expressions for recurring patterns or configure one-time invocations. You can set up flexible time windows for delivery, define retry limits, and set the maximum retention time for failed invocations.

Deploying the solution

Step 1: Deploy the AWS CloudFormation template

For this step, you deploy the template within the AWS account and Region where you want to test the solution.

  1. Choose the following Launch Stack button to launch an AWS CloudFormation stack in your account. Use the AWS Management Console navigation bar to choose the Region you want to deploy the stack in.

    Launch Stack

  2. Set the values for the following parameters based on how you want to use the solution:
    • On-demand malware scan sample tester — Amazon EC2 configuration
      • Create On-demand malware scan sample tester condition — Set the value to True to generate two EC2 instances to test the solution. These instances will serve as targets for an on-demand malware scan. One instance will contain EICAR malware sample files, which contain strings that will be detected as malware but aren’t malicious. The other instance won’t contain malware.
      • Tag key — Set the key that you want to be added to the test EC2 instances that are launched by this template.
      • Tag Value — Set the value that will be added to the test EC2 instances that are launched by this template.
      • Latest Amazon Linux instance used for tester — Leave as is.
    • Scheduled malware scan parameters
      • Tag keys and values parameter — Enter the tag key-value pairs that the scheduled scan will look for. If you populated the tag key and tag value parameters for the sample EC2 instance, then that should be one of the values in this parameter to ensure that the test instances are scanned.
      • EC2 instances ARNs to scan — [Optional] EC2 instances ID list that should be scanned when the scheduled scan runs.
      • EC2 instances state — Enter the state the EC2 instances can be in when selecting instances to scan.
    • AWS Scheduler parameters
      • Rate for the schedule scan to be run — defines how frequently the schedule should run. Valid options are minutes, hours, or days.
      • First time scheduled scan will run — Enter the day and time, in UTC format, when the first scheduled scan should run.
      • Time zone — Enter the time zone that the schedule start time should be applied to. Here is a list of valid time zone values.
  3. Scroll to the bottom of the Quick create stack screen and select the checkbox for I acknowledge that AWS CloudFormation might create IAM resources.
  4. Choose Create stack. The deployment of this CloudFormation stack will take 5–10 minutes.

After the CloudFormation stack has been deployed successfully, you can review and interact with the deployed solution.

Step 2: Amazon SNS topic subscription

As in use case 1, this solution supports using Amazon SNS to send a notification with the results of a malware scan. See the Amazon SNS subscription set up steps in use case 1 for guidance on setting up a subscription for receiving the results. For this use case, the naming convention of the Amazon SNS topic will include GuardDutyMalwareOnDemandScheduledScanTopic.

Step 3: Review scheduled scan configuration

For this use case, the parameters that were filled in during submission of the CloudFormation template build out an initial schedule for scanning EC2 instances. The following details describe the various components of the schedule and where you can make changes to influence how the schedule runs in the future.

  1. In the console, go to the EventBridge service. On the left side of the console under Scheduler, select Schedules. Select the scheduler that was created as part of the CloudFormation deployment.
    Figure 13: List of EventBridge schedules

    Figure 13: List of EventBridge schedules

  2. The Specify schedule detail page is where you can set the appropriate Timezone, Start date and time. In this walkthrough, this information for the schedule was provided when launching the CloudFormation template.
    Figure 14: EventBridge schedule detail

    Figure 14: EventBridge schedule detail

  3. On the Invoke page, the JSON will include the instance state, tags, and IDs, as well as the tags associated with the instance that were filled in during the deployment of the CloudFormation template. Make additional changes, as needed, and choose Next.
    Figure 15: EventBridge schedule Lambda invoke parameters

    Figure 15: EventBridge schedule Lambda invoke parameters

  4. Review and save schedule.
    Figure 16: EventBridge schedule summary

    Figure 16: EventBridge schedule summary

Step 4: Review malware scan results from GuardDuty

After a scheduled scan has been performed, the scan results will be available in the GuardDuty Malware console and generate a GuardDuty finding if malware is found. The output emails and access to the results in GuardDuty is the same as explained in use case 1.

Use case 3 – Initiating scans to support a security investigation

You might receive security signals or events about infrastructure and applications from multiple tools or sources in addition to Amazon GuardDuty. Investigations that arise from these security signals necessitate malware scans on specific EC2 instances that might be a source or target of a security event. With GuardDuty On-demand malware scan, you can incorporate a scan as part of your investigation workflow and use the output of the scan to drive the next steps in your investigation.

From the GuardDuty delegated administrator account, you can initiate a malware scan against EC2 instances in a member account which is associated with the administrator account. This enables you to initiate your malware scans from a centralized location and without the need for access to the account where the EC2 instance is deployed. Initiating a malware scan for an EC2 instance uses the same StartMalwareScan API described in the other use cases of this post. Depending on the tools that you’re using to support your investigations, you can also use the GuardDuty console to initiate a malware scan.

After a malware scan is run, malware findings will be available in the delegated administrator and member accounts, allowing you to get details and orchestrate the next steps in your investigation from a centralized location.

Figure 17 is an example of how a security investigation, using an on-demand malware scan, might function.

Figure 17: Example security investigation using GuardDuty On-demand malware scans

Figure 17: Example security investigation using GuardDuty On-demand malware scans

If you’re using GuardDuty as your main source of security findings for EC2 instances, the GuardDuty-initiated malware scan feature can also help facilitate an investigation workflow. With GuardDuty initiated malware scans, you can reduce the time between when an EC2 instance finding is created and when a malware scan of the instance is initiated, making the scan results available to your investigation workflows faster, helping you develop a remediation plan sooner.

Use case 4 – Malware scanning in a deployment pipeline

If you’re using deployment pipelines to build and deploy your infrastructure and applications, you want to make sure that what you’re deploying is secure. In cases where deployments involve third-party software, you want to be sure that the software is free of malware before deploying into environments where the malware could be harmful. This applies to software deployed directly onto an EC2 instance as well as containers that are deployed on an EC2 instance. In this case, you can use the on-demand malware scan in an EC2 instance in a secure test environment prior to deploying it in production. You can use the techniques described earlier in this post to design your deployment pipelines with steps that call the StartMalwareScan API and then check the results of the scan. Based on the scan results, you can decide if the deployment should continue or be stopped due to detected malware.

Running these scans before deployment into production can help to ensure the integrity of your applications and data and increase confidence that the production environment is free of significant security issues.

Figure 18 is an example of how malware scanning might look in a deployment pipeline for a containerized application.

Figure 18: Example deployment pipeline incorporating GuardDuty On-demand malware scan

Figure 18: Example deployment pipeline incorporating GuardDuty On-demand malware scan

In the preceding example the following steps are represented:

  1. A container image is built as part of a deployment pipeline.
  2. The container image is deployed into a test environment.
  3. From the test environment, a GuardDuty On-demand malware scan is initiated against the EC2 instance where the container image has been deployed.
  4. After the malware scan is complete, the results of the scan are evaluated.
  5. A decision is made on allowing the image to be deployed into production. If the image is approved, it’s deployed to production. If it’s rejected, a message is sent back to the owner of the container image for remediation of the identified malware.

Conclusion

Scanning for malware on your EC2 instances is key to maintaining that your instances are free of malware before they’re deployed to production, and if malware does find its way onto a deployed instance, it’s quickly identified so that it can be investigated and remediated.

This post outlines four use cases you can use with the On-demand malware scan feature: Scan based on tag, scan on a schedule, scan as part of an investigation, and scan in a deployment pipeline. The examples provided in this post are intended to provide a foundation that you can build upon to meet your specific use cases. You can use the provided code examples and sample architectures to enhance your operational and deployment processes.

To learn more about GuardDuty and its malware protection features, see the feature documentation and the service quotas for Malware protection.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Rodrigo Ferroni

Rodrigo is a Principal Security Specialist at AWS Enterprise Support. He’s certified in CISSP, an AWS Security Specialist, and AWS Solutions Architect Associate. He enjoys helping customers to continue adopting AWS security services to improve their security posture in the cloud. Outside of work, he loves to travel as much as he can. Every winter, he enjoys snowboarding with his friends.

Eduardo Ortiz Pineda

Eduardo Ortiz Pineda

Eduardo is a Senior Security Specialist at AWS Enterprise Support. He’s interested in different security topics, automation, and helping customers to improve their security posture. Outside of work, he spends his free time with family and friends, enjoying sports, reading, and traveling.

Author

Scott Ward

Scott is a Principal Solutions Architect with the External Security Services (ESS) product team and has been with Amazon for over 20 years. Scott provides technical guidance to customers on how to use security services to protect their AWS environments. Past roles include technical lead for the AWS Security Partner segment and member of the technical team for the Amazon.com global financial systems.

Howard Irabor

Howard Irabor

Howard is a Security Solutions Architect at AWS. Today, he’s devoted to assisting large-scale AWS customers in implementing and using AWS security services to lower risk and improve security. He’s a highly motivated person who relishes a good challenge. He’s an avid runner and soccer player in his spare time.

Blue/Green Deployments with Amazon ECS using Amazon CodeCatalyst

Post Syndicated from Hareesh Iyer original https://aws.amazon.com/blogs/devops/blue-green-deployments-with-amazon-ecs-using-amazon-codecatalyst/

Amazon CodeCatalyst is a modern software development service that empowers teams to deliver software on AWS easily and quickly. Amazon CodeCatalyst provides one place where you can plan, code, and build, test, and deploy your container applications with continuous integration/continuous delivery (CI/CD) tools.

In this post, we will walk-through how you can configure Blue/Green and canary deployments for your container workloads within Amazon CodeCatalyst.

Pre-requisites 

To follow along with the instructions, you’ll need:

  • An AWS account. If you don’t have one, you can create a new AWS account.
  • An Amazon Elastic Container Service (Amazon ECS) service using the Blue/Green deployment type. If you don’t have one, follow the Amazon ECS tutorial and complete steps 1-5.
  • An Amazon Elastic Container Registry (Amazon ECR) repository named codecatalyst-ecs-image-repo. Follow the Amazon ECR user guide to create one.
  • An Amazon CodeCatalyst space, with an empty Amazon CodeCatalyst project named codecatalyst-ecs-project and an Amazon CodeCatalyst environment called codecatalyst-ecs-environment. Follow the Amazon CodeCatalyst tutorial to set these up.
  • Follow the Amazon CodeCatalyst user guide to associate your account to the environment.

Walkthrough 

Now that you have setup an Amazon ECS cluster and configured Amazon CodeCatalyst to perform deployments, you can configure Blue/Green deployment for your workload. Here are the high-level steps:

  • Collect details of the Amazon ECS environment that you created in the prerequisites step.
  • Add source files for the containerized application to Amazon CodeCatalyst.
  • Create Amazon CodeCatalyst Workflow.
  • Validate the setup.

Step 1: Collect details from your ECS service and Amazon CodeCatalyst role

In this step, you will collect information from your prerequisites that will be used in the Blue/Green Amazon CodeCatalyst configuration further down this post.

If you followed the prerequisites tutorial, below are AWS CLI commands to extract values that are used in this post. You can run this on your local workstation or with AWS CloudShell in the same region you created your Amazon ECS cluster.

ECSCLUSTER='tutorial-bluegreen-cluster'
ECSSERVICE='service-bluegreen'

ECSCLUSTERARN=$(aws ecs describe-clusters --clusters $ECSCLUSTER --query 'clusters[*].clusterArn' --output text)
ECSSERVICENAME=$(aws ecs describe-services --services $ECSSERVICE --cluster $ECSCLUSTER  --query 'services[*].serviceName' --output text)
TASKDEFARN=$(aws ecs describe-services --services $ECSSERVICE --cluster $ECSCLUSTER  --query 'services[*].taskDefinition' --output text)
TASKROLE=$(aws ecs describe-task-definition --task-definition tutorial-task-def --query 'taskDefinition.executionRoleArn' --output text)
ACCOUNT=$(aws sts get-caller-identity --query "Account" --output text)

echo Account_ID value: $ACCOUNT
echo EcsRegionName value: $AWS_DEFAULT_REGION
echo EcsClusterArn value: $ECSCLUSTERARN
echo EcsServiceName value: $ECSSERVICENAME
echo TaskDefinitionArn value: $TASKDEFARN
echo TaskExecutionRoleArn value: $TASKROLE

Note down the values of Account_ID, EcsRegionName, EcsClusterArn, EcsServiceName, TaskDefinitionArn and TaskExecutionRoleArn. You will need these values in later steps.

Step 2: Add Amazon IAM roles to Amazon CodeCatalyst

In this step, you will create a role called CodeCatalystWorkflowDevelopmentRole-spacename to provide Amazon CodeCatalyst service permissions to build and deploy applications. This role is only recommended for use with development accounts and uses the AdministratorAccess AWS managed policy, giving it full access to create new policies and resources in this AWS account.

  • In Amazon CodeCatalyst, navigate to your space. Choose the Settings tab.
  • In the Navigation page, select AWS accounts. A list of account connections appears. Choose the account connection that represents the AWS account where you created your build and deploy roles.
  • Choose Manage roles from AWS management console.
  • The Add IAM role to Amazon CodeCatalyst space page appears. You might need to sign in to access the page.
  • Choose Create CodeCatalyst development administrator role in IAM. This option creates a service role that contains the permissions policy and trust policy for the development role.
  • Note down the role name. Choose Create development role.

Step 3: Create Amazon CodeCatalyst source repository

In this step, you will create a source repository in CodeCatalyst. This repository stores the tutorial’s source files, such as the task definition file.

  • In Amazon CodeCatalyst, navigate to your project.
  • In the navigation pane, choose Code, and then choose Source repositories.
  • Choose Add repository, and then choose Create repository.
  •  In Repository name, enter:

codecatalyst-advanced-deployment

  • Choose Create.

Step 4: Create Amazon CodeCatalyst Dev Environment

In this step, you will create a Amazon CodeCatalyst Dev environment to work on the sample application code and configuration in the codecatalyst-advanced-deployment repository. Learn more about Amazon CodeCatalyst dev environments in Amazon CodeCatalyst user guide.

  • In Amazon CodeCatalyst, navigate to your project.
  • In the navigation pane, choose Code, and then choose Source repositories.
  • Choose the source repository for which you want to create a dev environment.
  • Choose Create Dev Environment.
  • Choose AWS Cloud9 from the drop-down menu.
  • In Create Dev Environment and open with AWS Cloud9 page (Figure 1), choose Create to create a Cloud9 development environment.

Create Dev Environment in Amazon CodeCatalyst

Figure 1: Create Dev Environment in Amazon CodeCatalyst

AWS Cloud9 IDE opens on a new browser tab. Stay in AWS Cloud9 window to continue with Step 5.

Step 5: Add Source files to Amazon CodeCatalyst source repository

In this step, you will add source files from a sample application from GitHub to Amazon CodeCatalyst repository. You will be using this application to configure and test blue-green deployments.

  • On the menu bar at the top of the AWS Cloud9 IDE, choose Window, New Terminal or use an existing terminal window.
  • Download the Github project as a zip file, un-compress it and move it to your project folder by running the below commands in the terminal.

cd codecatalyst-advanced-deployment
wget -O SampleApp.zip https://github.com/build-on-aws/automate-web-app-amazon-ecs-cdk-codecatalyst/zipball/main/
unzip SampleApp.zip
mv build-on-aws-automate-web-app-amazon-ecs-cdk-codecatalyst-*/SampleApp/* .
rm -rf build-on-aws-automate-web-app-amazon-ecs-cdk-codecatalyst-*
rm SampleApp.zip

  • Update the task definition file for the sample application. Open task.json in the current directory. Find and replace “<arn:aws:iam::<account_ID>:role/AppRole> with the value collected from step 1: <TaskExecutionRoleArn>.
  • Amazon CodeCatalyst works with AWS CodeDeploy to perform Blue/Green deployments on Amazon ECS. You will create an Application Specification file, which will be used by CodeDeploy to manage the deployment. Create a file named appspec.yaml inside the codecatalyst-advanced-deployment directory. Update the <TaskDefinitionArn> with value from Step 1.
version: 0.0
Resources:
  - TargetService:
      Type: AWS::ECS::Service
      Properties:
        TaskDefinition: "<TaskDefinitionArn>"
        LoadBalancerInfo:
          ContainerName: "MyContainer"
          ContainerPort: 80
        PlatformVersion: "LATEST"
  • Commit the changes to Amazon CodeCatalyst repository by following the below commands. Update <your_email> and <your_name> with your email and name.

git config user.email "<your_email>"
git config user.name "<your_name>"
git add .
git commit -m "Initial commit"
git push

Step 6: Create Amazon CodeCatalyst Workflow

In this step, you will create the Amazon CodeCatalyst workflow which will automatically build your source code when changes are made. A workflow is an automated procedure that describes how to build, test, and deploy your code as part of a continuous integration and continuous delivery (CI/CD) system. A workflow defines a series of steps, or actions, to take during a workflow run.

  • In the navigation pane, choose CI/CD, and then choose Workflows.
  • Choose Create workflow. Select codecatalyst-advanced-deployment from the Source repository dropdown.
  • Choose main in the branch. Select Create (Figure 2). The workflow definition file appears in the Amazon CodeCatalyst console’s YAML editor.
    Create workflow page in Amazon CodeCatalyst

    Figure 2: Create workflow page in Amazon CodeCatalyst

  • Update the workflow by replacing the contents in the YAML editor with the below. Replace <Account_ID> with your AWS account ID. Replace <EcsRegionName>, <EcsClusterArn>, <EcsServiceName> with values from Step 1. Replace <CodeCatalyst-Dev-Admin-Role> with the Role Name from Step 3.
Name: BuildAndDeployToECS
SchemaVersion: "1.0"

# Set automatic triggers on code push.
Triggers:
  - Type: Push
    Branches:
      - main

Actions:
  Build_application:
    Identifier: aws/build@v1
    Inputs:
      Sources:
        - WorkflowSource
      Variables:
        - Name: region
          Value: <EcsRegionName>
        - Name: registry
          Value: <Account_ID>.dkr.ecr.<EcsRegionName>.amazonaws.com
        - Name: image
          Value: codecatalyst-ecs-image-repo
    Outputs:
      AutoDiscoverReports:
        Enabled: false
      Variables:
        - IMAGE
    Compute:
      Type: EC2
    Environment:
      Connections:
        - Role: <CodeCatalystPreviewDevelopmentAdministrator role>
          Name: "<Account_ID>"
      Name: codecatalyst-ecs-environment
    Configuration:
      Steps:
        - Run: export account=`aws sts get-caller-identity --output text | awk '{ print $1 }'`
        - Run: aws ecr get-login-password --region ${region} | docker login --username AWS --password-stdin ${registry}
        - Run: docker build -t appimage .
        - Run: docker tag appimage ${registry}/${image}:${WorkflowSource.CommitId}
        - Run: docker push --all-tags ${registry}/${image}
        - Run: export IMAGE=${registry}/${image}:${WorkflowSource.CommitId}
  RenderAmazonECStaskdefinition:
    Identifier: aws/ecs-render-task-definition@v1
    Configuration:
      image: ${Build_application.IMAGE}
      container-name: MyContainer
      task-definition: task.json
    Outputs:
      Artifacts:
        - Name: TaskDefinition
          Files:
            - task-definition*
    DependsOn:
      - Build_application
    Inputs:
      Sources:
        - WorkflowSource
  DeploytoAmazonECS:
    Identifier: aws/ecs-deploy@v1
    Configuration:
      task-definition: /artifacts/DeploytoAmazonECS/TaskDefinition/${RenderAmazonECStaskdefinition.task-definition}
      service: <EcsServiceName>
      cluster: <EcsClusterArn>
      region: <EcsRegionName>
      codedeploy-appspec: appspec.yaml
      codedeploy-application: tutorial-bluegreen-app
      codedeploy-deployment-group: tutorial-bluegreen-dg
      codedeploy-deployment-description: "Blue-green deployment for sample app"
    Compute:
      Type: EC2
      Fleet: Linux.x86-64.Large
    Environment:
      Connections:
        - Role: <CodeCatalyst-Dev-Admin-Role>
        # Add account id within quotes. Eg: "12345678"
          Name: "<Account_ID>"
      Name: codecatalyst-ecs-environment
    DependsOn:
      - RenderAmazonECStaskdefinition
    Inputs:
      Artifacts:
        - TaskDefinition
      Sources:
        - WorkflowSource

The workflow above does the following:

  • Whenever a code change is pushed to the repository, a Build action is triggered. The Build action builds a container image and pushes the image to the Amazon ECR repository created in Step 1.
  • Once the Build stage is complete, the Amazon ECS task definition is updated with the new ECR repository image.
  • The DeploytoECS action then deploys the new image to Amazon ECS using Blue/Green Approach.

To confirm everything was configured correctly, choose the Validate button. It should add a green banner with The workflow definition is valid at the top.

Select Commit to add the workflow to the repository (Figure 3)

Commit Workflow page in Amazon CodeCatalyst
Figure 3: Commit workflow page in Amazon CodeCatalyst

The workflow file is stored in a ~/.codecatalyst/workflows/ folder in the root of your source repository. The file can have a .yml or .yaml extension.

Let’s review our work, using the load balancer’s URL that you created during prerequisites, paste it into your browser. Your page should look similar to (Figure 4).

Sample Application (Blue Version)
Figure 4: Sample Application (Blue version)

Step 7: Validate the setup

To validate the setup, you will make a small change to the sample application.

  • Open Amazon CodeCatalyst dev environment that you created in Step 4.
  • Update your local copy of the repository. In the terminal run the command below.

git pull

  • In the terminal, navigate to /templates folder. Open index.html and search for “Las Vegas”. Replace the word with “New York”. Save the file.
  • Commit the change to the repository using the commands below.

git add .
git commit -m "Updating the city to New York"
git push

After the change is committed, the workflow should start running automatically. You can monitor of the workflow run in Amazon CodeCatalyst console (Figure 5)
Blue/Green Deployment Progress on Amazon CodeCatalyst

Figure 5: Blue/Green Deployment Progress on Amazon CodeCatalyst

You can also see the deployment status on the AWS CodeDeploy deployment page (Figure 6)

  • Going back to the AWS console.
  • In the upper left search bar, type in “CodeDeploy”.
  • In the left hand menu, select Deployments.

Blue/Green Deployment Progress on AWS CodeDeploy
Figure 6: Blue/Green Deployment Progress on AWS CodeDeploy

Let’s review our update, using the load balancer’s URL that you created during pre-requisites, paste it into your browser. Your page should look similar to (Figure 7).
Sample Application (Green version)

Figure 7: Sample Application (Green version)

Cleanup

If you have been following along with this workflow, you should delete the resources you deployed so you do not continue to incur charges.

  • Delete the Amazon ECS service and Amazon ECS cluster from AWS console.
  • Manually delete Amazon CodeCatalyst dev environment, source repository and project from your CodeCatalyst Space.
  • Delete the AWS CodeDeploy application through console or CLI.

Conclusion

In this post, we demonstrated how you can configure Blue/Green deployments for your container workloads using Amazon CodeCatalyst workflows. The same approach can be used to configure Canary deployments as well. Learn more about AWS CodeDeploy configuration for advanced container deployments in AWS CodeDeploy user guide.

William Cardoso

William Cardoso is a Solutions Architect at Amazon Web Services based in South Florida area. He has 20+ years of experience in designing and developing enterprise systems. He leverages his real world experience in IT operations to work with AWS customers providing architectural and best practice recommendations for new and existing solutions. Outside of work, William enjoys woodworking, walking and cooking for friends and family.

Piyush Mattoo

Piyush Mattoo is a Solution Architect for enterprises at Amazon Web Services. He is a software technology leader with over 15 years of experience building scalable and distributed software systems that require a combination of broad T-shaped skills across multiple technologies. He has an educational background in Computer Science with a Masters degree in Computer and Information Science from University of Massachusetts. He is based out of Southern California and current interests include outdoor camping and nature walks.

Hareesh Iyer

Hareesh Iyer is a Senior Solutions Architect at AWS. He helps customers build scalable, secure, resilient and cost-efficient architectures on AWS. He is passionate about cloud-native patterns, containers and microservices.

Simplify workforce identity management using IAM Identity Center and trusted token issuers

Post Syndicated from Roberto Migli original https://aws.amazon.com/blogs/security/simplify-workforce-identity-management-using-iam-identity-center-and-trusted-token-issuers/

AWS Identity and Access Management (IAM) roles are a powerful way to manage permissions to resources in the Amazon Web Services (AWS) Cloud. IAM roles are useful when granting permissions to users whose workloads are static. However, for users whose access patterns are more dynamic, relying on roles can add complexity for administrators who are faced with provisioning roles and making sure the right people have the right access to the right roles.

The typical solution to handle dynamic workforce access is the OAuth 2.0 framework, which you can use to propagate an authenticated user’s identity to resource services. Resource services can then manage permissions based on the user—their attributes or permissions—rather than building a complex role management system. AWS IAM Identity Center recently introduced trusted identity propagation based on OAuth 2.0 to support dynamic access patterns.

With trusted identity propagation, your requesting application obtains OAuth tokens from IAM Identity Center and passes them to an AWS resource service. The AWS resource service trusts tokens that Identity Center generates and grants permissions based on the Identity Center tokens.

What happens if the application you want to deploy uses an external OAuth authorization server, such as Okta Universal Directory or Microsoft Entra ID, but the AWS service uses IAM Identity Center? How can you use the tokens from those applications with your applications that AWS hosts?

In this blog post, we show you how you can use IAM Identity Center trusted token issuers to help address these challenges. You also review the basics of Identity Center and OAuth and how Identity Center enables the use of external OAuth authorization servers.

IAM Identity Center and OAuth

IAM Identity Center acts as a central identity service for your AWS Cloud environment. You can bring your workforce users to AWS and authenticate them from an identity provider (IdP) that’s external to AWS (such as Okta or Microsoft Entra), or you can create and authenticate the users on AWS.

Trusted identity propagation in IAM Identity Center lets AWS workforce identities use OAuth 2.0, helping applications that need to share who’s using them with AWS services. In OAuth, a client application and a resource service both trust the same authorization server. The client application gets an OAuth token for the user and sends it to the resource service. Because both services trust the OAuth server, the resource service can identify the user from the token and set permissions based on their identity.

AWS supports two OAuth patterns:

  • AWS applications authenticate directly with IAM Identity Center: Identity Center redirects authentication to your identity source, which generates OAuth tokens that the AWS managed application uses to access AWS services. This is the default pattern because the AWS services that support trusted identity propagation use Identity Center as their OAuth authorization server.
  • Third-party, non-AWS applications authenticate outside of AWS (typically to your IdP) and access AWS resources: During authentication, these third-party applications obtain an OAuth token from an OAuth authorization server outside of AWS. In this pattern, the AWS services aren’t connected to the same OAuth authorization server as the client application. To enable this pattern, AWS introduced a model called the trusted token issuer.

Trusted token issuer

When AWS services use IAM Identity Center as their authentication service, directory, and OAuth authorization server, the AWS services that use OAuth tokens require that Identity Center issues the tokens. However, most third-party applications federate with an external IdP and obtain OAuth tokens from an external authorization server. Although the identities in Identity Center and the external authorization server might be for the same person, the identities exist in separate domains, one in Identity Center, the other in the external authorization server. This is required to manage authorization of workforce identities with AWS services.

The trusted token issuer (TTI) feature provides a way to securely associate one identity from the external IdP with the other identity in IAM Identity Center.

When using third-party applications to access AWS services, there’s an external OAuth authorization server for the third-party application, and IAM Identity Center is the OAuth authorization server for AWS services; each has its own domain of users. The Identity Center TTI feature connects these two systems so that tokens from the external OAuth authorization server can be exchanged for tokens from Identity Center that AWS services can use to identify the user in the AWS domain of users. A TTI is the external OAuth authorization server that Identity Center trusts to provide tokens that third-party applications use to call AWS services, as shown in Figure 1.

Figure 1: Conceptual model using a trusted token issuer and token exchange

Figure 1: Conceptual model using a trusted token issuer and token exchange

How the trust model and token exchange work

There are two levels of trust involved with TTIs. First, the IAM Identity Center administrator must add the TTI, which makes it possible to exchange tokens. This involves connecting Identity Center to the Open ID Connect (OIDC) discovery URL of the external OAuth authorization server and defining an attribute-based mapping between the user from the external OAuth authorization server and a corresponding user in Identity Center. Second, the applications that exchange externally generated tokens must be configured to use the TTI. There are two models for how tokens are exchanged:

  • Managed AWS service-driven token exchange: A third-party application uses an AWS driver or API to access a managed AWS service, such as accessing Amazon Redshift by using Amazon Redshift drivers. This works only if the managed AWS service has been designed to accept and exchange tokens. The application passes the external token to the AWS service through an API call. The AWS service then makes a call to IAM Identity Center to exchange the external token for an Identity Center token. The service uses the Identity Center token to determine who the corresponding Identity Center user is and authorizes resource access based on that identity.
  • Third-party application-driven token exchange: A third-party application not managed by AWS exchanges the external token for an IAM Identity Center token before calling AWS services. This is different from the first model, where the application that exchanges the token is the managed AWS service. An example is a third-party application that uses Amazon Simple Storage Service (Amazon S3) Access Grants to access S3. In this model, the third-party application obtains a token from the external OAuth authorization server and then calls Identity Center to exchange the external token for an Identity Center token. The application can then use the Identity Center token to call AWS services that use Identity Center as their OAuth authorization server. In this case, the Identity Center administrator must register the third-party application and authorize it to exchange tokens from the TTI.

TTI trust details

When using a TTI, IAM Identity Center trusts that the TTI authenticated the user and authorized them to use the AWS service. This is expressed in an identity token or access token from the external OAuth authorization server (the TTI).

These are the requirements for the external OAuth authorization server (the TTI) and the token it creates:

  • The token must be a signed JSON Web Token (JWT). The JWT must contain a subject (sub) claim, an audience (aud) claim, an issuer (iss), a user attribute claim, and a JWT ID (JTI) claim.
    • The subject in the JWT is the authenticated user and the audience is a value that represents the AWS service that the application will use.
    • The audience claim value must match the value that is configured in the application that exchanges the token.
    • The issuer claim value must match the value configured in the issuer URL in the TTI.
    • There must be a claim in the token that specifies a user attribute that IAM Identity Center can use to find the corresponding user in the Identity Center directory.
    • The JWT token must contain the JWT ID claim. This claim is used to help prevent replay attacks. If a new token exchange is attempted after the initial exchange is complete, IAM Identity Center rejects the new exchange request.
  • The TTI must have an OIDC discovery URL that IAM Identity Center can use to obtain keys that it can use to verify the signature on JWTs created by your TTI. Identity Center appends the suffix /.well-known/openid-configuration to the provider URL that you configure to identify where to fetch the signature keys.

Note: Typically, the IdP that you use as your identity source for IAM Identity Center is your TTI. However, your TTI doesn’t have to be the IdP that Identity Center uses as an identity source. If the users from a TTI can be mapped to users in Identity Center, the tokens can be exchanged. You can have as many as 10 TTIs configured for a single Identity Center instance.

Details for applications that exchange tokens

Your OAuth authorization server service (the TTI) provides a way to authorize a user to access an AWS service. When a user signs in to the client application, the OAuth authorization server generates an ID token or an access token that contains the subject (the user) and an audience (the AWS services the user can access). When a third-party application accesses an AWS service, the audience must include an identifier of the AWS service. The third-party client application then passes this token to an AWS driver or an AWS service.

To use IAM Identity Center and exchange an external token from the TTI for an Identity Center token, you must configure the application that will exchange the token with Identity Center to use one or more of the TTIs. Additionally, as part of the configuration process, you specify the audience values that are expected to be used with the external OAuth token.

  • If the applications are managed AWS services, AWS performs most of the configuration process. For example, the Amazon Redshift administrator connects Amazon Redshift to IAM Identity Center, and then connects a specific Amazon Redshift cluster to Identity Center. The Amazon Redshift cluster exchanges the token and must be configured to do so, which is done through the Amazon Redshift administrative console or APIs and doesn’t require additional configuration.
  • If the applications are third-party and not managed by AWS, your IAM Identity Center administrator must register the application and configure it for token exchange. For example, suppose you create an application that obtains an OAuth token from Okta Universal Directory and calls S3 Access Grants. The Identity Center administrator must add this application as a customer managed application and must grant the application permissions to exchange tokens.

How to set up TTIs

To create new TTIs, open the IAM Identity Center console, choose Settings, and then choose Create trusted token issuer, as shown in Figure 2. In this section, I show an example of how to use the console to create a new TTI to exchange tokens with my Okta IdP, where I already created my OIDC application to use with my new IAM Identity Center application.

Figure 2: Configure the TTI in the IAM Identity Center console

Figure 2: Configure the TTI in the IAM Identity Center console

TTI uses the issuer URL to discover the OpenID configuration. Because I use Okta, I can verify that my IdP discovery URL is accessible at https://{my-okta-domain}.okta.com/.well-known/openid-configuration. I can also verify that the OpenID configuration URL responds with a JSON that contains the jwks_uri attribute, which contains a URL that lists the keys that are used by my IdP to sign the JWT tokens. Trusted token issuer requires that both URLs are publicly accessible.

I then configure the attributes I want to use to map the identity of the Okta user with the user in IAM Identity Center in the Map attributes section. I can get the attributes from an OIDC identity token issued by Okta:

{
    "sub": "00u22603n2TgCxTgs5d7",
    "email": "<masked>",
    "ver": 1,
    "iss": "https://<masked>.okta.com",
    "aud": "123456nqqVBTdtk7890",
    "iat": 1699550469,
    "exp": 1699554069,
    "jti": "ID.MojsBne1SlND7tCMtZPbpiei9p-goJsOmCiHkyEhUj8",
    "amr": [
        "pwd"
    ],
    "idp": "<masked>",
    "auth_time": 1699527801,
    "at_hash": "ZFteB9l4MXc9virpYaul9A"
}

I’m requesting a token with an additional email scope, because I want to use this attribute to match against the email of my IAM Identity Center users. In most cases, your Identity Center users are synchronized with your central identity provider by using automatic provisioning with the SCIM protocol. In this case, you can use the Identity Center external ID attribute to match with oid or sub attributes. The only requirement for TTI is that those attributes create a one-to-one mapping between the two IdPs.

Now that I have created my TTI, I can associate it with my IAM Identity Center applications. As explained previously, there are two use cases. For the managed AWS service-driven token exchange use case, use the service-specific interface to do so. For example, I can use my TTI with Amazon Redshift, as shown in Figure 3:

Figure 3: Configure the TTI with Amazon Redshift

Figure 3: Configure the TTI with Amazon Redshift

I selected Okta as the TTI to use for this integration, and I now need to configure the audclaim value that the application will use to accept the token. I can find it when creating the application from the IdP side–in this example, the value is 123456nqqVBTdtk7890, and I can obtain it by using the preceding example OIDC identity token.

I can also use the AWS Command Line Interface (AWS CLI) to configure the IAM Identity Center application with the appropriate application grants:

aws sso put-application-grant \
    --application-arn "<my-application-arn>" \
    --grant-type "urn:ietf:params:oauth:grant-type:jwt-bearer" \
    --grant '
    {
        "JwtBearer": { 
            "AuthorizedTokenIssuers": [
                {
                    "TrustedTokenIssuerArn": "<my-tti-arn>", 
                    "AuthorizedAudiences": [
                        "123456nqqVBTdtk7890"
                    ]
                 }
            ]
       }
    }'

Perform a token exchange

For AWS service-driven use cases, the token exchange between your IdP and IAM Identity Center is performed automatically by the service itself. For third-party application-driven token exchange, such as when building your own Identity Center application with S3 Access Grants, your application performs the token exchange by using the Identity Center OIDC API action CreateTokenWithIAM:

aws sso-oidc create-token-with-iam \  
    --client-id "<my-application-arn>" \ 
    --grant-type "urn:ietf:params:oauth:grant-type:jwt-bearer" \
    --assertion "<jwt-from-idp>"

This action is performed by an IAM principal, which then uses the result to interact with AWS services.

If successful, the result looks like the following:

{
    "accessToken": "<idc-access-token>",
    "tokenType": "Bearer",
    "expiresIn": 3600,
    "idToken": "<jwt-idc-identity-token>",
    "issuedTokenType": "urn:ietf:params:oauth:token-type:access_token",
    "scope": [
        "sts:identity_context",
        "openid",
        "aws"
    ]
}

The value of the scope attribute varies depending on the IAM Identity Center application that you’re interacting with, because it defines the permissions associated with the application.

You can also inspect the idToken attribute because it’s JWT-encoded:

{
    "aws:identity_store_id": "d-123456789",
    "sub": "93445892-f001-7078-8c38-7f2b978f686f",
    "aws:instance_account": "12345678912",
    "iss": "https://identitycenter.amazonaws.com/ssoins-69870e74abba8440",
    "sts:audit_context": "<sts-token>",
    "aws:identity_store_arn": "arn:aws:identitystore::12345678912:identitystore/d-996701d649",
    "aud": "20bSatbAF2kiR7lxX5Vdp2V1LWNlbnRyYWwtMQ",
    "aws:instance_arn": "arn:aws:sso:::instance/ssoins-69870e74abba8440",
    "aws:credential_id": "<masked>",
    "act": {
      "sub": "arn:aws:sso::12345678912:trustedTokenIssuer/ssoins-69870e74abba8440/c38448c2-e030-7092-0f0a-b594f83fcf82"
    },
    "aws:application_arn": "arn:aws:sso::12345678912:application/ssoins-69870e74abba8440/apl-0ed2bf0be396a325",
    "auth_time": "2023-11-10T08:00:08Z",
    "exp": 1699606808,
    "iat": 1699603208
  }

The token contains:

  • The AWS account and the IAM Identity Center instance and application that accepted the token exchange
  • The unique user ID of the user that was matched in IAM Identity Center (attribute sub)

AWS services can now use the STS Audit Context token (found in the attribute sts:audit_context) to create identity-aware sessions with the STS API. You can audit the API calls performed by the identity-aware sessions in AWS CloudTrail, by inspecting the attribute onBehalfOf within the field userIdentity. In this example, you can see an API call that was performed with an identity-aware session:

"userIdentity": {
    ...
    "onBehalfOf": {
        "userId": "93445892-f001-7078-8c38-7f2b978f686f",
        "identityStoreArn": "arn:aws:identitystore::425341151473:identitystore/d-996701d649"
    }
}

You can thus quickly filter actions that an AWS principal performs on behalf of your IAM Identity Center user.

Troubleshooting TTI

You can troubleshoot token exchange errors by verifying that:

  • The OpenID discovery URL is publicly accessible.
  • The OpenID discovery URL response conforms with the OpenID standard.
  • The OpenID keys URL referenced in the discovery response is publicly accessible.
  • The issuer URL that you configure in the TTI exactly matches the value of the iss scope that your IdP returns.
  • The user attribute that you configure in the TTI exists in the JWT that your IdP returns.
  • The user attribute value that you configure in the TTI matches exactly one existing IAM Identity Center user on the target attribute.
  • The aud scope exists in the token returned from your IdP and exactly matches what is configured in the requested IAM Identity Center application.
  • The jti claim exists in the token returned from your IdP.
  • If you use an IAM Identity Center application that requires user or group assignments, the matched Identity Center user is already assigned to the application or belongs to a group assigned to the application.

Note: When an IAM Identity Center application doesn’t require user or group assignments, the token exchange will succeed if the preceding conditions are met. This configuration implies that the connected AWS service requires additional security assignments. For example, Amazon Redshift administrators need to configure access to the data within Amazon Redshift. The token exchange doesn’t grant implicit access to the AWS services.

Conclusion

In this blog post, we introduced the trust token issuer feature of IAM Identity Center and what it offers, how it’s configured, and how you can use it to integrate your IdP with AWS services. You learned how to use TTI with AWS-managed applications and third-party applications by configuring the appropriate parameters. You also learned how to troubleshoot token-exchange issues and audit access through CloudTrail.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS IAM Identity Center re:Post or contact AWS Support.

Roberto Migli

Roberto Migli

Roberto is a Principal Solutions Architect at AWS. Roberto supports global financial services customers, focusing on security and identity and access management. In his free time, he enjoys building electronic gadgets, learning about space, and spending time with his family.

Ron Cully

Ron Cully

Ron is a Principal Product Manager at AWS where he leads feature and roadmap planning for workforce identity products at AWS. Ron has over 20 years of industry experience in product and program management in networking and directory related products. He is passionate about delivering secure, reliable solutions that help make it simple for customers to migrate directory-aware applications and workloads to the cloud.

Rafael Koike

Rafael Koike

Rafael is a Principal Solutions Architect supporting enterprise customers in the Southeast and is a Storage SME. Rafael has a passion to build, and his expertise in security, storage, networking, and application development has been instrumental in helping customers move to the cloud quickly and securely.