Tag Archives: Amazon EC2

Optimizing Cloud Infrastructure Cost and Performance with Starburst on AWS

Post Syndicated from Kinnar Kumar Sen original https://aws.amazon.com/blogs/architecture/optimizing-cloud-infrastructure-cost-and-performance-with-starburst-on-aws/

Amazon Web Services (AWS) Cloud is elastic, convenient to use, easy to consume, and makes it simple to onboard workloads. Because of this simplicity, the cost associated with onboarding workloads is sometimes overlooked.

There is a notion that when an organization moves its workload to the cloud, agility, scalability, performance, and cost issues will disappear. While this may be true for agility and scalability, you must optimize your workload. You can do this with services like Amazon EC2 Auto Scaling via Amazon Elastic Compute Cloud (Amazon EC2) and Amazon EC2 Spot Instances to realize the performance and cost benefits the cloud offers.

In this blog post, we show you how Starburst Enterprise (Starburst) addressed a sudden increase in cost for their data analytics platform as they grew their internal teams and scaled out their infrastructure. After reviewing their architecture and deployments with AWS specialist architects, Starburst and AWS concluded that they could take the following steps to greatly reduce costs:

  1. Use Spot Instances to run workloads.
  2. Add Amazon EC2 Auto Scaling into their training and demonstration environments, because the Starburst platform is designed to elastically scale up and down.

For analytics workloads, when you rein in costs, you typically rein in performance. Starburst and AWS worked together to balance the cost and performance of Starburst’s data analytics platform while also harnessing the flexibility, scalability, security, and performance of the cloud.

What is Starburst Enterprise?

Starburst provides a Massively Parallel Processing SQL (MPPSQL) engine based on open source Trino. It is an analytics platform that provides the cornerstone in customers’ intelligent data mesh and offers the following benefits and services:

  • The platform gives you a single point to access, monitor, and secure your data mesh.
  • The platform gives you options for your data compute. You no longer have to wait on data migrations or extract, transform, and load (ETL), there is no vendor lock-in, and there is no need to swap out your existing analytics tools.
  • Starburst Stargate (Stargate) ensures that large jobs are completed within each data domain of your data mesh. Only the result set is retrieved from the domain.
    • Stargate reduces data output, which reduces costs and increases performance.
    • Data governance policies can also be applied uniquely in each data domain, ensuring security compliance and federation.

As shown in Figure 1, there are many connectors for input and output that ensure you experience improved performance and security.

Starburst platform

Figure 1. Starburst platform

Integrating Starburst Enterprise with AWS

As shown in Figure 2, Starburst Enterprise uses AWS services to deliver elastic scaling and optimize cost. The platform is architected with decoupled storage and compute. This allows the platform to scale as needed to analyze petabytes of data.

The platform can be deployed via AWS CloudFormation or Amazon Elastic Kubernetes Service (Amazon EKS). Starburst on AWS allows you to run analytic queries across AWS data sources and on-premises systems such as Teradata and Oracle.

Deployment architecture of Starburst platform on AWS

Figure 2. Deployment architecture of Starburst platform on AWS

Amazon EC2 Auto Scaling

Enterprises have diverse analytic workloads; their compute and memory requirements vary with time. Starburst uses Amazon EKS and Amazon EC2 Auto Scaling to elastically scale compute resources to meet the demands of their analytics workloads.

  • Amazon EC2 Auto Scaling ensures that you have the compute capacity for your workloads to handle the load elastically. It is used to architect sophisticated, elastic, and resilient applications on the AWS Cloud.
    • Starburst uses the scheduled scaling feature of Amazon EC2 Auto Scaling to scale the cluster up/down based on time. Thus, they incur no costs when the cluster is not in use.
  • Amazon EKS is a fully managed Kubernetes service that allows you to run Kubernetes on AWS without needing to install, operate, and maintain your own Kubernetes control plane.

Scaling cloud resource consumption on demand has a major impact on controlling cloud costs. Starburst supports scaling down elastically, which means removing compute resources doesn’t impact the underlying processes.

Amazon EC2 Spot Instances

Spot Instances let you take advantage of unused EC2 capacity in the AWS Cloud. They are available at up to a 90% discount compared to On-Demand Instance prices. If EC2 needs capacity for On-Demand Instance usage, Spot Instances can be interrupted by Amazon EC2 with a two-minute notification. There are many ways to handle the interruption to ensure that the application is well architected for resilience and fault tolerance.

Starburst has integrated Spot Instances as a part of the Amazon EKS managed node groups to cost optimize the analytics workloads. This best practice of instance diversification is implemented by using the integration eksctl and instance selector with dry-run flag. This creates a list of instances of same size (vCPU/Mem ratio) and uses them in the underlying node groups.

Same size instances are required to make best use of Kubernetes Cluster Autoscaler, which is used to manage the size of the cluster.

Scaling down, handling interruptions, and provisioning compute

“Scaling in” an active application is tricky, but Starburst was built with resiliency in mind, and it can effectively manage shut downs.

Spot Instances are an ideal compute option because Starburst can handle potential interruptions natively. Starburst also uses Amazon EKS managed node groups to provision nodes in the cluster. This requires significantly less operational effort compared to using self-managed node groups. It allows Starburst to enforce best practices like capacity optimized allocation strategy, capacity rebalancing, and instance diversification.

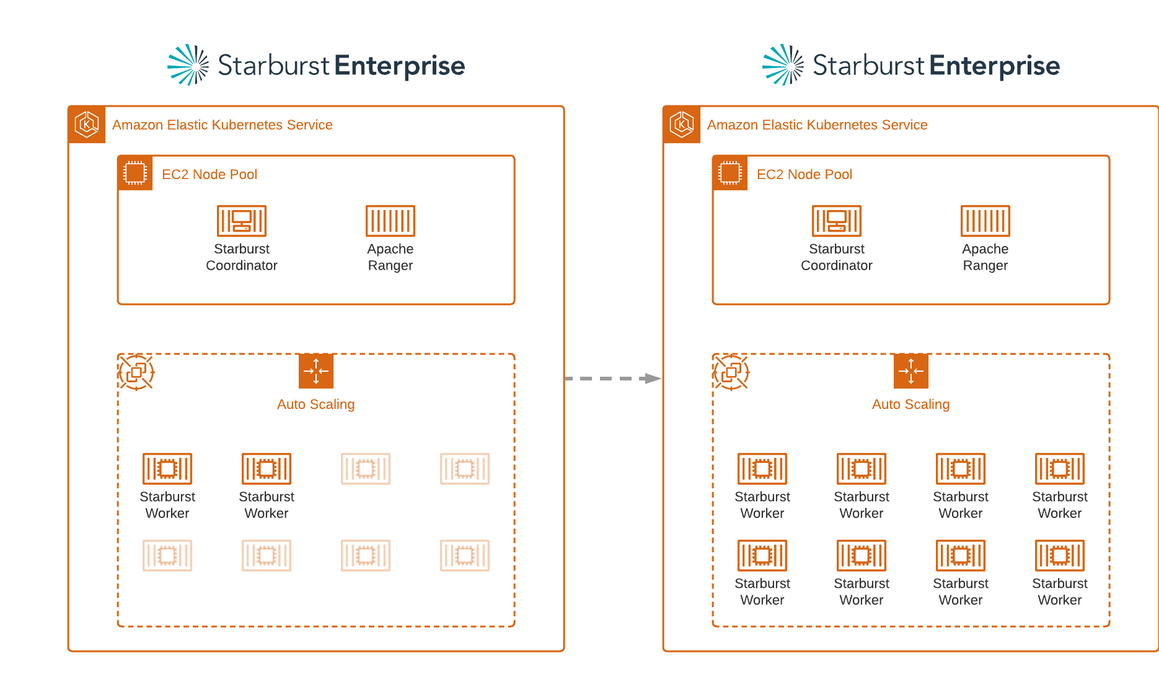
When you need to “scale out” the deployment, Amazon EKS and Amazon EC2 Auto Scaling help to provision capacity, as depicted in Figure 3.
Depicting “scale out” in a Starburst deployment

Figure 3. Depicting “scale out” in a Starburst deployment

Benefits realized from using AWS services

In a short period, Starburst was able to increase the number of people working on AWS. They added five times the number of Solutions Architects, they have previously. Additionally, in their initial tests of their new deployment architecture, their Solutions Architects were able to complete up to three times the amount of work than they had been able to previously. Even after the workload increased more than 15 times, with two simple changes they only had a slight increase in total cost.

This cost and performance optimization allows Starburst to be more productive internally and realize value for each dollar spent. This further justified investing more into building out infrastructure footprint.

Conclusion

In building their architecture with AWS, Starburst realized the importance of having a robust and comprehensive cloud administration plan that they can implement and manage going forward. They are now able to balance the cloud costs with performance and stability, even after considering the SLA requirements. Starburst is planning to teach their customers about the Spot Instance and Amazon EC2 Auto Scaling best practices to ensure they maintain a cost and performance optimized cloud architecture.

If you want to see the Starburst data analytics platform in action, you can get a free trial in the AWS Marketplace: Starburst Data Free Trial.
Disaster Recovery (DR) for a Third-party Interactive Voice Response on AWS

Post Syndicated from Priyanka Kulkarni original https://aws.amazon.com/blogs/architecture/disaster-recovery-dr-for-a-third-party-interactive-voice-response-on-aws/

Voice calling systems are prevalent and necessary to many businesses today. They are usually designed to provide a 24×7 helpline support across multiple domains and use cases. Reliability and availability of such systems are important for a good customer experience. The thoughtful design of a cost-optimized solution will allow your business to sustain the system into the future.

We address a scenario in which you are mandated to host the workload on a corporate data center (DC), and configure the backup site on Amazon Web Services (AWS). Since the primary objective of a backup site is disaster recovery (DR) management, this site is often referred to as a DR site.

Disaster Recovery on AWS

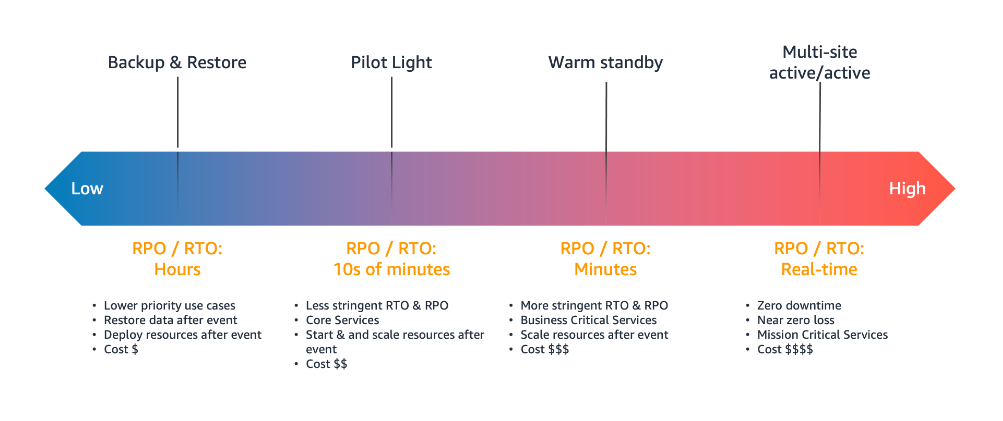
DR strategy defines the recovery objectives for downtime and data loss. The workload has a recovery time objective (RTO) and a recovery point objective (RPO). RTO is the maximum acceptable delay between the interruption of service and the restoration of service. RPO is the maximum acceptable amount of time since the last data recovery point. AWS defines four DR strategies in increasing order of complexity, and decreasing order of RTO and RPO. These are backup and restore, active/passive (pilot light or warm standby), or active/active.

Figure 1. Disaster recovery (DR) options

Figure 1. Disaster recovery (DR) options

In our use case, the DR site on AWS must serve the user traffic with RPO and RTO in seconds. Warm standby is the optimal choice in this case. It is a scaled-down version of a fully functional environment, and is always running in the cloud.

Amazon Connect is an omnichannel cloud contact center that helps you provide great customer service at a lower cost. But in some situations, Amazon Connect may not be available. In other cases, the customer may want to use their home developed or third-party contact center application. Our solution is designed to help in both these scenarios.

This architecture enables customers facing challenges of cost overhead with redundant Session Initiation Protocol (SIP) trunks for the DC and DR sites. It allows you to optimize your spend and yet retain a reliable workflow.

SIP trunk communication on AWS

Let’s see how the SIP trunk termination on the AWS network handles the failover scenario of a third-party IVR application installed on Amazon EC2 at the DR site.

There will be two connections made from the AWS Direct Connect location (DX). The first will be for a point-to-point connectivity between the corporate DC and the AWS DR site. The second connection will be originating from the multiplexer (MUX) of the telecom provider who is providing you the SIP trunk.

The telecom provider will lay the SIP trunk from its MUX to the customer router at the DX location. At this point, the mode of communication becomes IP-based. The telecom provider will send the call to the IP address attached to the Network Load Balancer (NLB) in Amazon Virtual Private Cloud (VPC).

Figure 2. Communication circuitry at telecom side

Figure 2. Communication circuitry at telecom side

AWS Network Load Balancers can now distribute traffic to AWS resources using their IP addresses and instance IDs as targets. You can also distribute the traffic with on-premises resources over AWS Direct Connect. Load balancing across AWS and on-premises resources using the same load balancer streamlines migrate-to-cloud, burst-to-cloud, or failover-to-cloud.

In the backup site, the NLB will point to the Session Border Controller (SBC). This is a special-purpose device that protects and regulates IP communications flows. You can bring your own SBC, or you can use an SBC offered in the AWS Marketplace.

Best practices for high availability of IVR solution on AWS

  • Configure the multiple Availability Zone (Multi-AZ) SBC setup
  • Make sure that the telecom provider for the SIP trunk is different from the internet service provider (ISP). This is for last mile connectivity for the DC from Direct Connect
  • Consider redundancy for Direct Connect by using a Site-to-Site VPN tunnel
Figure 3. Solution architecture of DR on AWS for a third-party IVR solution

Figure 3. Solution architecture of DR on AWS for a third-party IVR solution

Communication flow for an IVR solution deployed on a corporate DC and its DR on AWS

  1. The callers are received on the telecom providers SIP line, which terminates on the AWS Direct Connect location.
  2. At the DX location, you will configure a route in the AWS router to send the traffic to the IP address of the NLB. The NLB should be configured to perform health checks on the virtual machine in your on-premises DC. Based on these health checks, the NLB will do the routing and the failover.
  3. In a live scenario with successful health checks at the DC, the NLB will forward the call to the IP of the on-premises virtual machine. This is where the IVR application will be installed.
  4. The communication between the NLB in Amazon VPC and the virtual machine in DC, will happen over Direct Connect.
  5. In a DR scenario, the NLB will failover the communication to SBCs in Amazon VPC.

Conclusion

This solution is useful when a third-party IVR system is deployed in a corporate data center, and the passive DR site is hosted on AWS. Cost optimization on telecom components is an important aspect of this design. AWS Direct Connect provides dedicated connectivity to the AWS environment, from 50 Mbps up to 10 Gbps. This gives you managed and controlled latency. It also provides provisioned bandwidth, so your workload can connect to AWS resources in a reliable, scalable, and cost-effective way.

The solution in this blog explains the end-to-end flow of communication, from the user to the IVR agents. It also provides insights into managing failover and failback between DR and the DR site.

Further Reading:

Optimize costs by up to 70% with new Amazon T3 Dedicated Hosts

Post Syndicated from Emma White original https://aws.amazon.com/blogs/compute/optimize-costs-by-up-to-70-with-new-amazon-t3-dedicated-hosts/

This post is written by Andy Ward, Senior Specialist Solutions Architect, and Yogi Barot, Senior Specialist Solutions Architect.

Customers have been taking advantage of Amazon Elastic Compute Cloud (Amazon EC2) Dedicated Hosts to enable them to use their eligible software licenses from vendors such as Microsoft and Oracle since the feature launched in 2015. Amazon EC2 Dedicated Hosts have gained new features over the years. For example, Customers can launch different-sized instances within the same instance family and use AWS License Manager to track and manage software licenses. Host Resource Groups have enabled customers to take advantage of automated host management. Further, the ability to use license included Windows Server on Dedicated Hosts has opened up new possibilities for cost-optimization.

The ability to bring your own license (BYOL) to Amazon EC2 Dedicated Hosts has been an invaluable cost-optimization tool for customers. Since the introduction of Dedicated Hosts on Amazon EC2, customers have requested additional flexibility to further optimize their ability to save on licensing costs on AWS. We listened to that feedback, and are now launching a new type of Amazon EC2 Dedicated Host to enable additional cost savings.

In this blog post, we discuss how our customers can benefit from the newest member of our Amazon EC2 Dedicated Hosts family – the T3 Dedicated Host. The T3 Dedicated Host is the first Amazon EC2 Dedicated Host to support general-purpose burstable T3 instances, providing the most cost-efficient way of using eligible BYOL software on dedicated hardware.

Introducing T3 Dedicated Hosts

When we talk to our customers about BYOL, we often hear the following:

  • We currently run our workloads on-premises and want to move our workloads to AWS with BYOL.
  • We currently benefit from oversubscribing CPU on our on-premises hosts, and want to retain our oversubscription benefits when bringing our eligible BYOL software to AWS.
  • How can we further cost-optimize our AWS environment, increasing the flexibility and cost effectiveness of our licenses?
  • Some of our virtual servers use minimal resources. How can we use smaller instance sizes with BYOL?

T3 Dedicated Hosts differ from our other EC2 Dedicated Hosts. Where our traditional EC2 Dedicated Hosts provide fixed CPU resources, T3 Dedicated Hosts support burstable instances capable of sharing CPU resources, providing a baseline CPU performance and the ability to burst when needed. Sharing CPU resources, also known as oversubscription, is what enables a single T3 Dedicated Host to support up to 4x more instances than comparable general-purpose Dedicated Hosts. This increase in the number of instances supported can enable customers to save on licensing and infrastructure costs by as much as 70%.

Advantages of T3 Dedicated Hosts

 T3 Dedicated Hosts drive a lower total cost of ownership (TCO) by delivering a higher instance density than any other EC2 Dedicated Host. Burstable T3 instances allow customers to consolidate a higher number of instances with low-to-moderate average CPU utilization on fewer hosts than ever before.

T3 Dedicated Hosts also offer smaller instance sizes, in a greater number of vCPU and memory combinations, than other EC2 Dedicated Hosts. Smaller instance sizes can contribute to lower TCO and help deliver consolidation ratios equivalent to or greater than on-premises hosts.

AWS hypervisor management features provide consistent performance for customer workloads. Customers can choose between a wide selection of instance configurations with different vCPU and memory sizes, mixing and matching instances sizes from t3.nano up to t3.2xlarge

You can use your existing eligible per-socket, per-core, or per-VM software licenses, including licenses for Windows Server, SQL Server, SUSE Linux Enterprise Server and Red Hat Enterprise Linux. As licensing terms often change over time, we recommend checking eligibility for BYOL with your license vendor.

You can track your license usage using your license configuration in AWS License Manager. For more information, see the Track your license using AWS License Manager blog post and the Manage Software Licenses with AWS License Manager video on YouTube.

When to use T3 Dedicated Hosts

T3 Dedicated Hosts are best suited for running instances such as small and medium databases and application servers, virtual desktops, and development and test environments. In common with on-premises hypervisor hosts that allow CPU oversubscription, T3 Dedicated Hosts are less suitable for workloads that experience correlated CPU burst patterns.

T3 Dedicated Hosts support all instance sizes of the T3 family, with a wide variety of CPU and RAM ratios. Additionally, as T3 Dedicated Hosts are powered by the AWS Nitro System, they support multiple instance sizes on a single host. Customers can run up to 192 instances on a single T3 Dedicated Host, each capable of supporting multiple processes. The maximum instance limits are shown in the following table:

Instance Family Sockets Physical Cores nano micro small medium large xlarge 2xlarge
t3 2 48 192 192 192 192 96 48 24


Any combination of T3 instance types can be run, up to the memory limit of the host (768GB). Examples of supported blended instance type combinations are:

  • 132 t3.small and 60 t3.large
  • 128 t3.small and 64 t3.large
  • 24 t3.xlarge and 12 t3.2xlarge

Use Cases

If you are looking for ways to decrease your license costs and host footprint in order to achieve the lowest TCO, then using T3 Dedicated Hosts enables a set of previously unavailable scenarios to help you achieve this goal. The ability to run a greater number of instances per host compared to existing Dedicated Hosts leads directly to lower licensing and infrastructure costs on AWS, for suitable BYOL workloads.

The following three scenarios are typical examples of benefits that can be realized by customers using T3 Dedicated Hosts.

Retaining Existing Server Consolidation Ratios While Migrating to AWS

On-premises, you are taking advantage of the fact that you can easily oversubscribe your physical CPUs on VMware hosts and achieve high-levels of consolidation. As you can license Windows Server on a per-physical-core basis, you only need to license the physical cores of the VMware hosts, and not the vCPUs of the Windows Server virtual machines.

  • You are currently running 7 x 48 core VMware Hosts on-premises.
  • Each host is running 150 x 2 vCPU low average-CPU-utilization Windows Server virtual machines.
  • You have Windows Server Datacenter licenses that are eligible for BYOL to AWS.

In this scenario, T3 Dedicated Hosts enable you to achieve similar, or better, levels of consolidation. Additionally, the number of Windows Server Datacenter licenses required in order to bring your workloads to AWS is reduced from 336 cores to 288 cores – a saving of 14%.

On-Premises VMware Hosts T3 Dedicated Hosts Savings
Physical Servers (48 Cores) 7 6
2 vCPU VMs per Host 150 192
Total number of VMs 1000 1000
Total Windows Server Datacenter Licenses (Per Core) 336 288 14%

Reducing License Requirements While Migrating To AWS

On-premises you are taking advantage of the fact that you can easily oversubscribe your physical CPUs on VMware hosts and achieve high-levels of consolidation. You can now achieve far greater levels of consolidation by moving your virtual machines to T3 Dedicated Hosts, which have double the amount of RAM compared to your current on-premises VMware hosts.

  • You are currently using 10 x 36 core, 384GB RAM VMware Hosts on-premises.
  • Each host is running 96 x 2 vCPU, 4GB RAM low average-CPU-utilization Windows Server virtual machines.

By taking advantage of oversubscription and the increased RAM on T3 Dedicated Hosts, you can now achieve far greater levels of consolidation. Additionally, you are able to reduce the number of Windows Server Datacenter licenses required for BYOL. In this scenario, you can achieve a license reduction from 360 cores to 240 cores – a 33% saving.

On-Premises VMware Hosts T3 Dedicated Hosts Savings
Physical Servers 10 5
Physical Cores per Host 36 48
RAM per Host (GB) 384 768
2 vCPU, 4GB RAM VMs per Host 96 192
Total number of VMs 960 960
Total Windows Server Datacenter Licenses (Per Core) = Number of Servers * Physical Core Count 10 * 36 = 360 5 * 48 = 240 33%

Reducing License and Infrastructure Cost by Migrating from C5 Dedicated Hosts to T3 Dedicated Hosts

In this scenario, you are taking advantage of the fact that you can bring your own eligible Windows Server and SQL Server licenses to AWS for use on Dedicated Hosts. However, as your instances all have low average-CPU-utilization, your current C5 Dedicated Hosts, with fixed CPU resources, are largely underutilized.

  • You are currently using C5 EC2 Dedicated Hosts on AWS with eligible Windows Server Datacenter licenses and SQL Server 2017 Enterprise Edition (BYOL).
  • Each host is running 36 x 2 vCPU low average-CPU-utilization Windows Server virtual machines.

By migrating to T3 Dedicated Hosts, you can achieve a substantial reduction in licensing costs. As the total number of physical cores requiring licensing is reduced, you can benefit from a corresponding reduction in the number of SQL Server Enterprise Edition licenses required – a saving of 71%.

C5 Dedicated Hosts T3 Dedicated Hosts Savings
Total Number of Hosts Required 28 6
2 vCPU, 4GB VMs per Host 36 192
Total number of VMs 1008 1008
Total SQL Server EE Licenses = Number of Servers * Physical Core Count 36 * 28 = 1008 48 * 6 = 288 71%

Conclusion

In this blog post, we described the new T3 Dedicated Hosts and how they help customers benefit from running more instances per host in BYOL scenarios. We showed that heavily oversubscribed on-premises environments can be migrated to T3 Dedicated Hosts on AWS while lowering existing licensing and infrastructure costs. We further showed how significant licensing and infrastructure savings can be realized by moving existing workloads from EC2 Dedicated Hosts with fixed CPU resources to new T3 Dedicated Hosts.

Visit the Dedicated Hosts, AWS License Manager and host resource group pages to get started with saving costs on licensing and infrastructure.

AWS can help you assess how your company can get the most out of cloud. Join the millions of AWS customers that trust us to migrate and modernize their most important applications in the cloud. To learn more on modernizing Windows Server or SQL Server, visit Windows on AWS. Contact us to start your migration journey today.

New – Amazon EC2 VT1 Instances for Live Multi-stream Video Transcoding

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-vt1-instances-for-live-multi-stream-video-transcoding/

Global demand for video content has been rapidly increasing and now has the major audiences of Internet and mobile network traffic. Over-the-top streaming services such as Twitch continue to see an explosion of content creators who are seeking live delivery with great image quality, while live event broadcasters are increasingly looking to embrace agile cloud infrastructure to reduce costs without sacrificing reliability, and efficiently scale with demand.

Today, I am happy to announce the general availability of Amazon EC2 VT1 instances that are designed to provide the best price performance for multi-stream video transcoding with resolutions up to 4K UHD. These VT1 instances feature Xilinx® Alveo™ U30 media accelerator transcoding cards with accelerated H.264/AVC and H.265/HEVC codecs and provide up to 30% better price per stream compared to the latest GPU-based EC2 instances and up to 60% better price per stream compared to the latest CPU-based EC2 instances.
Customers with their own live broadcast and streaming video pipelines can use VT1 instances to transcode video streams with resolutions up to 4K UHD. VT1 instances feature networking interfaces of up to 25 Gbps that can ingest multiple video streams over IP with low latency and low jitter. This capability makes it possible for these customers to fully embrace scalable, cost-effective, and resilient infrastructure.

Amazon EC2 VT1 Instance Type
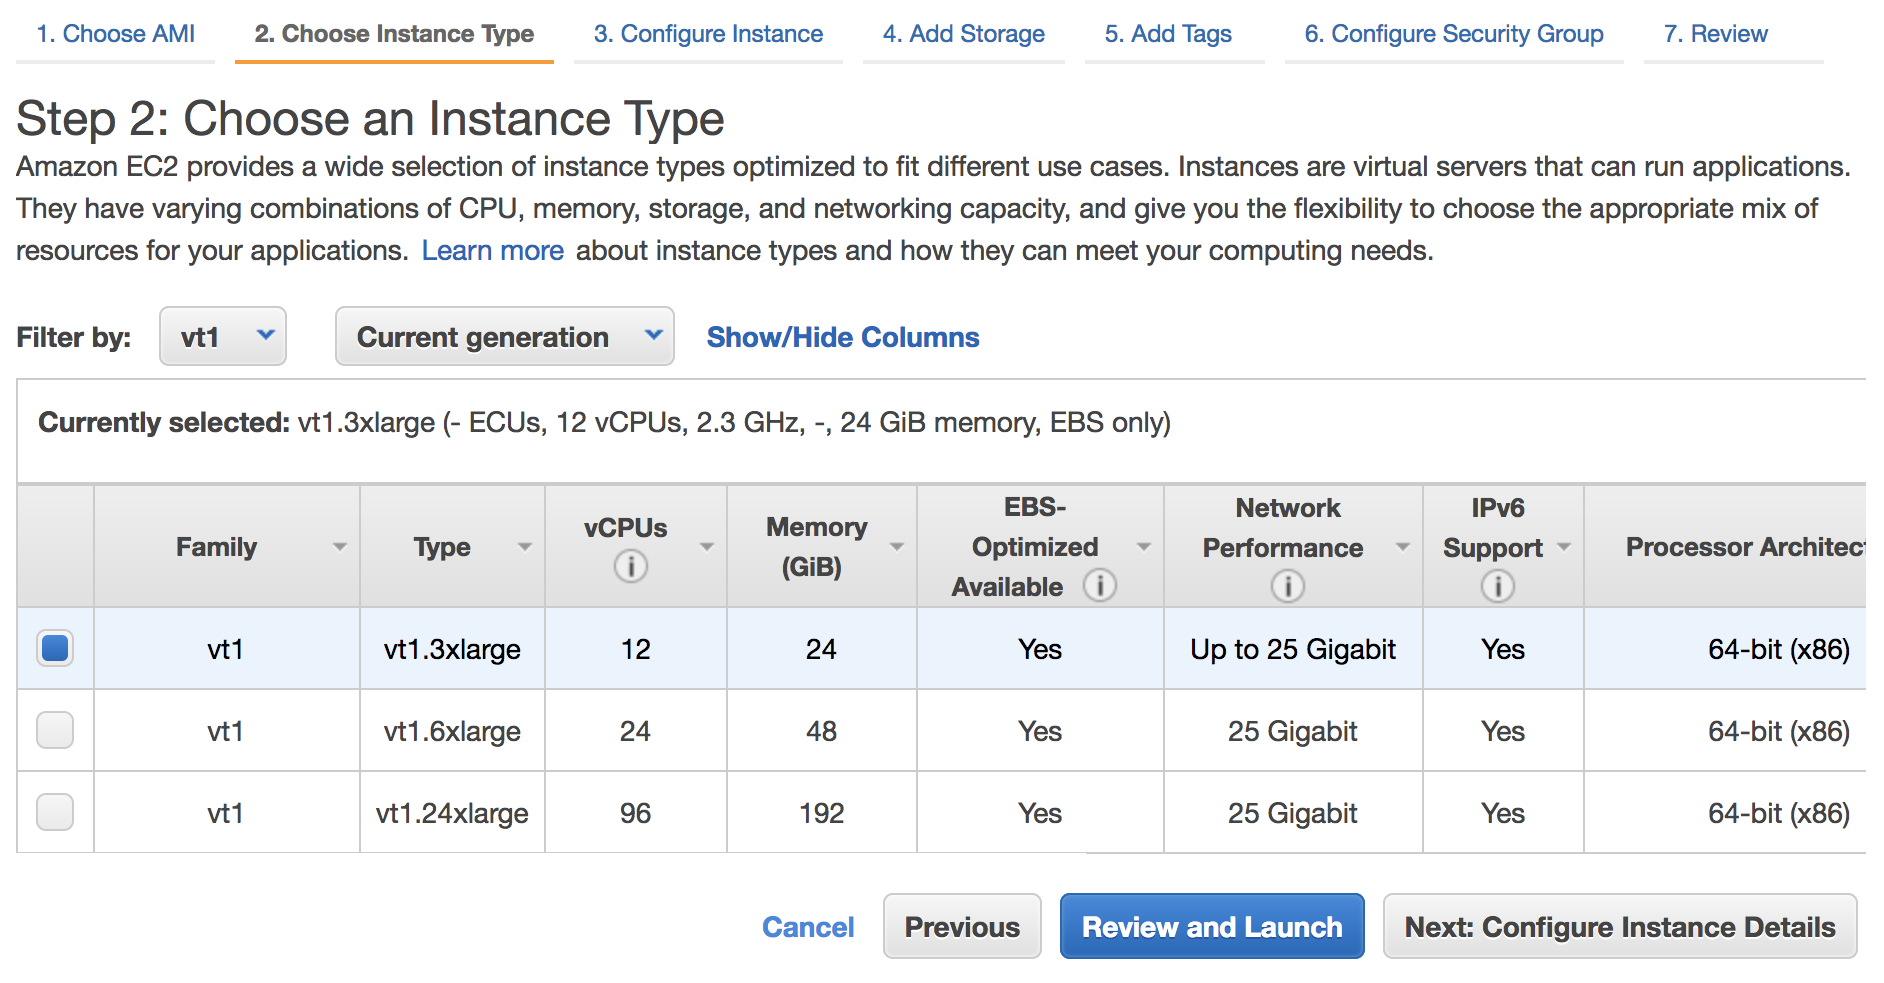
EC2 VT1 instances are available in three sizes. The accelerated H.264/AVC and H.265/HEVC codecs are integrated into Xilinx Zynq ZU7EV SoCs. Each Xilinx® Alveo™ U30 media transcoding accelerator card contains two Zynq SoCs.

Instance size vCPUs Xilinx U30 card Memory Network bandwidth EBS-optimized bandwidth 1080p60 Streams per instance
vt1.3xlarge 12 1 24GB Up to 25 Gbps Up to 4.75 Gbps 8
vt1.6xlarge 24 2 48GB 25 Gbps 4.75 Gbps 16
vt1.24xlarge 96 8 192GB 25 Gbps 19 Gbps 64

The VT1 instances are suitable for transcoding multiple streams per instance. The streams can be processed independently in parallel or mixed (picture-in-picture, side-by-side, transitions). The vCPU cores help with implementing image processing, audio processing, and multiplexing. The Xilinx® Alveo™ U30 card can simultaneously output multiple streams at different resolutions (1080p, 720p, 480p, and 360p) and in both H.264 and H.265.

Each VT1 instance can be configured to produce parallel encoding with different settings, resolutions and transmission bit rate (“ABR ladders“). For example, a 4K UHD stream can be encoded at 60 frames per second with H.265 for high resolution display. Multiple lower resolutions can be encoded with H.264 for delivery to standard displays.

Get Started with EC2 VT1 Instances
You can now launch VT1 instances in the Amazon EC2 console, AWS Command Line Interface (AWS CLI), or using an SDK with the Amazon EC2 API.

We provide a number of sample video processing pipelines for the VT1 instances. There are tutorials and code examples in the GitHub repository that cover how to tune the codecs for image quality and transcoding latency, call the runtime for the U30 cards directly from your own applications, incorporate video filters such as titling and watermarking, and deploy with container orchestration frameworks.

Xilinx provides the “Xilinx Video Transcoding SDK” which includes:

VT1 instances can be coupled with Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Kubernetes Service (Amazon EKS) to efficiently scale transcoding workloads and with Amazon CloudFront to deliver content globally. VT1 instances can also be launched with Amazon Machine Images (AMIs) and containers developed by AWS Marketplace partners, such as Nginx for supplemental video processing functionality.

You can complement VT1 instances with AWS Media Services for reliable packaging and origination of transcoded content. To learn more, you can use a solution library of Live Streaming on AWS to build a live video workflow using these AWS services.

Available Now
Amazon EC2 VT1 instances are now available in the US East (N. Virginia), US West (Oregon), Europe (Ireland), Asia Pacific (Tokyo) Regions. To learn more, visit the EC2 VT1 instance page. Please send feedback to the AWS forum for Amazon EC2 or through your usual AWS support contacts.

– Channy

Enabling parallel file systems in the cloud with Amazon EC2 (Part I: BeeGFS)

Post Syndicated from Ben Peven original https://aws.amazon.com/blogs/compute/enabling-parallel-file-systems-in-the-cloud-with-amazon-ec2-part-i-beegfs/

This post was authored by AWS Solutions Architects Ray Zaman, David Desroches, and Ameer Hakme.

In this blog series, you will discover how to build and manage your own Parallel Virtual File System (PVFS) on AWS. In this post you will learn how to deploy the popular open source parallel file system, BeeGFS, using AWS D3en and I3en EC2 instances. We will also provide a CloudFormation template to automate this BeeGFS deployment.

A PVFS is a type of distributed file system that distributes file data across multiple servers and provides concurrent data access to multiple execution tasks of an application. PVFS focuses on high-performance access to large datasets. It consists of a server process and a client library, which allows the file system to be mounted and used with standard utilities. PVFS on the Linux OS originated in the 1990’s and today several projects are available including Lustre, GlusterFS, and BeeGFS. Workloads such as shared storage for video transcoding and export, batch processing jobs, high frequency online transaction processing (OLTP) systems, and scratch storage for high performance computing (HPC) benefit from the high throughput and performance provided by PVFS.

Implementation of a PVFS can be complex and expensive. There are many variables you will want to take into account when designing a PVFS cluster including the number of nodes, node size (CPU, memory), cluster size, storage characteristics (size, performance), and network bandwidth. Due to the difficulty in estimating the correct configuration, systems procured for on-premises data centers are typically oversized, resulting in additional costs, and underutilized resources. In addition, the hardware procurement process is lengthy and the installation and maintenance of the hardware adds additional overhead.

AWS makes it easy to run and fully manage your parallel file systems by allowing you to choose from a variety of Amazon Elastic Compute Cloud (EC2) instances. EC2 instances are available on-demand and allow you to scale your workload as needed. AWS storage-optimized EC2 instances offer up to 60 TB of NVMe SSD storage per instance and up to 336 TB of local HDD storage per instance. With storage-optimized instances, you can easily deploy PVFS to support workloads requiring high-performance access to large datasets. You can test and iterate on different instances to find the optimal size for your workloads.

D3en instances leverage 2nd-generation Intel Xeon Scalable Processors (Cascade Lake) and provide a sustained all core frequency up to 3.1 GHz. These instances provide up to 336 TB of local HDD storage (which is the highest local storage capacity in EC2), up to 6.2 GiBps of disk throughput, and up to 75 Gbps of network bandwidth.

I3en instances are powered by 1st or 2nd generation Intel® Xeon® Scalable (Skylake or Cascade Lake) processors with 3.1 GHz sustained all-core turbo performance. These instances provide up to 60 TB of NVMe storage, up to 16 GB/s of sequential disk throughput, and up to 100 Gbps of network bandwidth.

BeeGFS, originally released by ThinkParQ in 2014, is an open source, software defined PVFS that runs on Linux. You can scale the size and performance of the BeeGFS file-system by configuring the number of servers and disks in the clusters up to thousands of nodes.

BeeGFS architecture

D3en instances offer HDD storage while I3en instances offer NVMe SSD storage. This diversity allows you to create tiers of storage based on performance requirements. In the example presented in this post you will use four D3en.8xlarge (32 vCPU, 128 GB, 16x14TB HDD, 50 Gbit) and two I3en.12xlarge (48 vCPU, 384 GB, 4 x 7.5-TB NVMe) instances to create two storage tiers. You may choose different sizes and quantities to meet your needs. The I3en instances, with SSD, will be configured as tier 1 and the D3en instances, with HDD, will be configured as tier 2. One disk from each instance will be formatted as ext4 and used for metadata while the remaining disks will be formatted as XFS and used for storage. You may choose to separate metadata and storage on different hosts for workloads where these must scale independently. The array will be configured RAID 0, since it will provide maximum performance. Software replication or other RAID types can be employed for higher durability.

BeeGFS architecture

Figure 1: BeeGFS architecture

You will deploy all instances within a single VPC in the same Availability Zone and subnet to minimize latency. Security groups must be configured to allow the following ports:

  • Management service (beegfs-mgmtd): 8008
  • Metadata service (beegfs-meta): 8005
  • Storage service (beegfs-storage): 8003
  • Client service (beegfs-client): 8004

You will use the Debian Quick Start Amazon Machine Image (AMI) as it supports BeeGFS. You can enable Amazon CloudWatch to capture metrics.

How to deploy the BeeGFS architecture

Follow the steps below to create the PVFS described above. For automated deployment, use the CloudFormation template located at AWS Samples.

  1. Use the AWS Management Console or CLI to deploy one D3en.8xlarge instance into a VPC as described above.
  2. Log in to the instance and update the system:
    • sudo apt update
    • sudo apt upgrade
  3. Install the XFS utilities and load the kernel module:
    • sudo apt-get -y install xfsprogs
    • sudo modprobe -v xfs

Format the first disk ext4 as it is used for metadata, the rest are formatted xfs. The disks will appear as “nvme???” which actually represent the HDD drives on the D3en instances.

4. View a listing of available disks:

    • sudo lsblk

5. Format hard disks:

    • sudo mkfs -t ext4 /dev/nvme0n1
    • sudo mkfs -t xfs /dev/nvme1n1
    • Repeat this command for disks nvme2n1 through nvme15n1

6. Create file system mount points:

    • sudo mkdir /disk00
    • sudo mkdir /disk01
    • Repeat this command for disks disk02 through disk15

7. Mount the filesystems:

    • sudo mount /dev/nvme0n1 /disk00
    • sudo mount /dev/nvme0n1 /disk01
    • Repeat this command for disks disk02 through disk15

Repeat steps 1 through 7 on the remaining nodes. Remember to account for fewer disks for i3en.12xlarge instances or if you decide to use different instance sizes.

8. Add the BeeGFS Repo to each node:

    • sudo apt-get -y install gnupg
    • wget https://www.beegfs.io/release/beegfs_7.2.3/dists/beegfs-deb10.list
    • sudo cp beegfs-deb10.list /etc/apt/sources.list.d/
    • sudo wget -q https://www.beegfs.io/release/latest-stable/gpg/DEB-GPG-KEY-beegfs -O- | sudo apt-key add -
    • sudo apt update

9. Install BeeGFS management (node 1 only):

    • sudo apt-get -y install beegfs-mgmtd
    • sudo mkdir /beegfs-mgmt
    • sudo /opt/beegfs/sbin/beegfs-setup-mgmtd -p /beegfs-mgmt/beegfs/beegfs_mgmtd

10. Install BeeGFS metadata and storage (all nodes):

    • sudo apt-get -y install beegfs-meta beegfs-storage beegfs-meta beegfs-client beegfs-helperd beegfs-utils
    • # -s is unique ID based on node - change this!, -m is hostname of management server
    • sudo /opt/beegfs/sbin/beegfs-setup-meta -p /disk00/beegfs/beegfs_meta -s 1 -m ip-XXX-XXX-XXX-XXX
    • # Change -s to nodeID and -i to (nodeid)0(disk), -m is hostname of management server
    • sudo /opt/beegfs/sbin/beegfs-setup-storage -p /disk01/beegfs_storage -s 1 -i 101 -m ip-XXX-XXX-XXX-XXX
    • sudo /opt/beegfs/sbin/beegfs-setup-storage -p /disk02/beegfs_storage -s 1 -i 102 -m ip-XXX-XXX-XXX-XXX
    • Repeat this last command for the remaining disks disk03 through disk15

11. Start the services:

    • #Only on node1
    • sudo systemctl start beegfs-mgmtd
    • #All servers
    • sudo systemctl start beegfs-meta
    • sudo systemctl start beegfs-storage

At this point, your BeeGFS cluster is running and ready for use by a client system. The client system requires BeeGFS client software in order to mount the cluster.

12. Deploy an m5n.2xlarge instance into the same subnet as the PVFS cluster.

13. Log in to the instance, install, and configure the client:

    • sudo apt update
    • sudo apt upgrade
    • sudo apt-get -y install gnupg
    • #Need linux sources for client compilation
    • sudo apt-get -y install linux-source
    • sudo apt-get -y install linux-headers-4.19.0-14-all
    • wget https://www.beegfs.io/release/beegfs_7.2.3/dists/beegfs-deb10.list
    • sudo cp beegfs-deb10.list /etc/apt/sources.list.d/
    • sudo wget -q https://www.beegfs.io/release/latest-stable/gpg/DEB-GPG-KEY-beegfs -O- | sudo apt-key add -
    • sudo apt update
    • sudo apt-get -y install beegfs-client beegfs-helperd beegfs-utils
    • sudo /opt/beegfs/sbin/beegfs-setup-client -m ip-XXX-XXX-XXX-XX # use the ip address of the management node
    • sudo systemctl start beegfs-helperd
    • sudo systemctl start beegfs-client

14. Create the storage pools:

    • sudo beegfs-ctl --addstoragepool —desc="tier1" —targets=501,502,503,601,602,603
    • sudo beegfs-ctl --addstoragepool --desc="tier2" --targets=101,102,103,104,105,106,107,108,109,110,111,112,113,114,115,201,202,203,204,205,206,207,208,209,210,
      211,212,213,214,215,301,302,303,304,305,306,307,308,309,310,311,312,313,314,315,401,402,403,404,405,406,407,
      408,409,410,411,412,413,414,415
    • sudo beegfs-ctl --liststoragepools
    • Pool ID Pool Description                      Targets                 Buddy Groups
    • ======= ================== ============================ ============================
      • Default
      • tier1 501,502,503,601,602,603
      • tier2 101,102,103,104,105,106,107,
        • 108,109,110,111,112,113,114,
        • 115,201,202,203,204,205,206,
        • 207,208,209,210,211,212,213,
        • 214,215,301,302,303,304,305,
        • 306,307,308,309,310,311,312,
        • 313,314,315,401,402,403,404,
        • 405,406,407,408,409,410,411,
        • 412,413,414,415

15. Mount the pools to the file system:

    • sudo beegfs-ctl --setpattern --storagepoolid=2 /mnt/beegfs/tier1
    • sudo beegfs-ctl --setpattern --storagepoolid=3 /mnt/beegfs/tier2

The BeeGFS PVFS is now ready to be used by the client system.

How to test your new BeeGFS PVFS

BeeGFS provides StorageBench to evaluate the performance of BeeGFS on the storage targets. This benchmark measures the streaming throughput of the underlying file system and devices independent of the network performance. To simulate client I/O, this benchmark generates read/write locally on the servers without any client communication.

It is possible to benchmark specific targets or all targets together using the “servers” parameter. A “read” or “write” parameter sets the type pf test to perform. The “threads” parameter is set to the number of storage devices.

Try the following commands to test performance:

Write test (1x d3en):

sudo beegfs-ctl --storagebench --servers=1 --write --blocksize=512K —size=20G —threads=15

Write test (4x d3en):

sudo beegfs-ctl --storagebench --alltargets --write --blocksize=512K —size=20G —threads=15

Read test (4x d3en):

sudo beegfs-ctl --storagebench --servers=1,2,3,4 --read --blocksize=512K --size=20G --threads=15

Write test (1x i3en):

sudo beegfs-ctl --storagebench --servers=5 --write --blocksize=512K --size=20G --threads=3

Read test (2x i3en):

sudo beegfs-ctl --storagebench --servers=5,6 --read --blocksize=512K —size=20G —threads=3

StorageBench is a great way to test what the potential performance of a given environment looks like by reducing variables like network throughput and latency, but you may want to test in a more real-world fashion. For this, tools like ‘fio’ can generate mixed read/write workloads against files on the client BeeGFS mountpoint.

First, we need to define which directory goes to which Storage Pool (tier) by setting a pattern:

sudo beegfs-ctl --setpattern --storagepoolid=2 /mnt/beegfs/tier1 sudo beegfs-ctl --setpattern --storagepoolid=3 /mnt/beegfs/tier2

You can see how a file gets striped across the various disks in a pool by adding a file and running the command:

sudo beegfs-ctl —getentryinfo /mnt/beegfs/tier1/myfile.bin

Install fio:

sudo apt-get install -y fio

Now you can run a fio test against one of the tiers.  This example command runs eight threads running a 75/25 read/write workload against a 10-GB file:

sudo fio --numjobs=8 --randrepeat=1 --ioengine=libaio --direct=1 --gtod_reduce=1 --name=test --filename=/mnt/beegfs/tier1/test --bs=512k --iodepth=64 --size=10G --readwrite=randrw --rwmixread=75

Cleaning up

To avoid ongoing charges for resources you created, you should:

Conclusion

In this blog post we demonstrated how to build and manage your own BeeGFS Parallel Virtual File System on AWS. In this example, you created two storage tiers using the I3en and D3en. The I3en was used as the first tier for SSD storage and the D3en was used as a second tier for HDD storage. By using two different tiers, you can optimize performance to meet your application requirements.

Amazon EC2 storage-optimized instances make it easy to deploy the BeeGFS Parallel Virtual File System. Using combinations of SSD and HDD storage available on the I3en and D3en instance types, you can achieve the capacity and performance needed to run the most demanding workloads. Read more about the D3en and I3en instances.

Field Notes: Automate Disaster Recovery for AWS Workloads with Druva

Post Syndicated from Girish Chanchlani original https://aws.amazon.com/blogs/architecture/field-notes-automate-disaster-recovery-for-aws-workloads-with-druva/

This post was co-written by Akshay Panchmukh, Product Manager, Druva and Girish Chanchlani, Sr Partner Solutions Architect, AWS.

The Uptime Institute’s Annual Outage Analysis 2021 report estimated that 40% of outages or service interruptions in businesses cost between $100,000 and $1 million, while about 17% cost more than $1 million. To guard against this, it is critical for you to have a sound data protection and disaster recovery (DR) strategy to minimize the impact on your business. With the greater adoption of the public cloud, most companies are either following a hybrid model with critical workloads spread across on-premises data centers and the cloud or are all in the cloud.

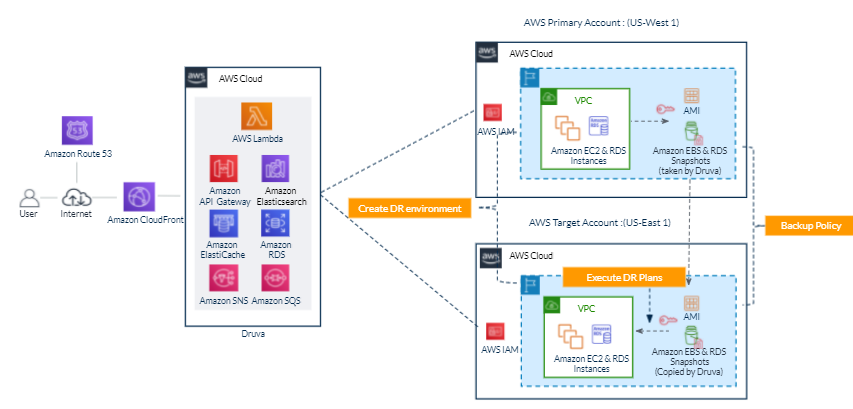
In this blog post, we focus on how Druva, a SaaS based data protection solution provider, can help you implement a DR strategy for your workloads running in Amazon Web Services (AWS). We explain how to set up protection of AWS workloads running in one AWS account, and fail them over to another AWS account or Region, thereby minimizing the impact of disruption to your business.

Overview of the architecture

In the following architecture, we describe how you can protect your AWS workloads from outages and disasters. You can quickly set up a DR plan using Druva’s simple and intuitive user interface, and within minutes you are ready to protect your AWS infrastructure.

Figure 1. Druva architecture

Druva’s cloud DR is built on AWS using native services to provide a secure operating environment for comprehensive backup and DR operations. With Druva, you can:

  • Seamlessly create cross-account DR sites based on source sites by cloning Amazon Virtual Private Clouds (Amazon VPCs) and their dependents.
  • Set up backup policies to automatically create and copy snapshots of Amazon Elastic Compute Cloud (Amazon EC2) and Amazon Relational Database Service (Amazon RDS) instances to DR Regions based on recovery point objective (RPO) requirements.
  • Set up service level objective (SLO) based DR plans with options to schedule automated tests of DR plans and ensure compliance.
  • Monitor implementation of DR plans easily from the Druva console.
  • Generate compliance reports for DR failover and test initiation.

Other notable features include support for automated runbook initiation, selection of target AWS instance types for DR, and simplified orchestration and testing to help protect and recover data at scale. Druva provides the flexibility to adopt evolving infrastructure across geographic locations, adhere to regulatory requirements (such as, GDPR and CCPA), and recover workloads quickly following disasters, helping meet your business-critical recovery time objectives (RTOs). This unified solution offers taking snapshots as frequently as every five minutes, improving RPOs. Because it is a software as a service (SaaS) solution, Druva helps lower costs by eliminating traditional administration and maintenance of storage hardware and software, upgrades, patches, and integrations.

We will show you how to set up Druva to protect your AWS workloads and automate DR.

Step 1: Log into the Druva platform and provide access to AWS accounts

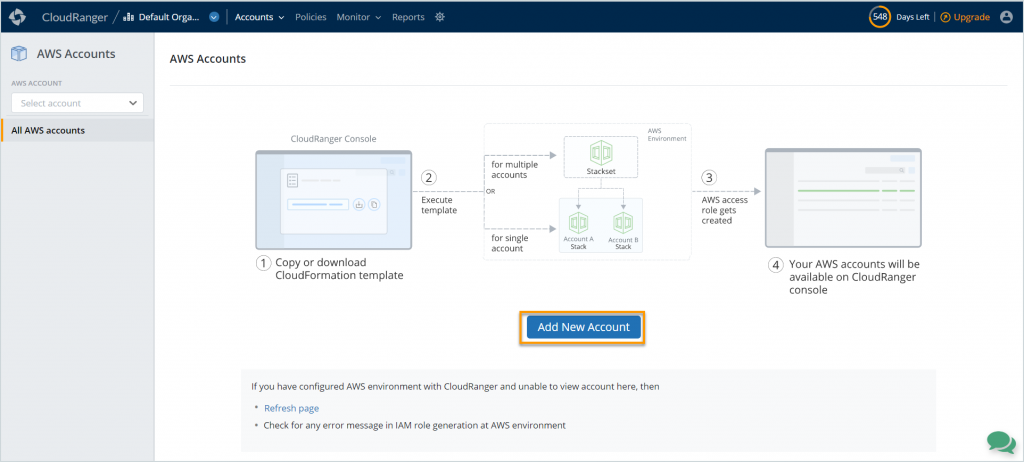
After you sign into the Druva Cloud Platform, you will need to grant Druva third-party access to your AWS account by pressing Add New Account button, and following the steps as shown in Figure 2.

Figure 2. Add AWS account information

Druva uses AWS Identity and Access Management (IAM) roles to access and manage your AWS workloads. To help you with this, Druva provides an AWS CloudFormation template to create a stack or stack set that generates the following:

  • IAM role
  • IAM instance profile
  • IAM policy

The generated Amazon Resource Name (ARN) of the IAM role is then linked to Druva so that it can run backup and DR jobs for your AWS workloads. Note that Druva follows all security protocols and best practices recommended by AWS. All access permissions to your AWS resources and Regions are controlled by IAM.

After you have logged into Druva and set up your account, you can now set up DR for your AWS workloads. The following steps will allow you to set up DR for AWS infrastructure.

Step 2: Identify the source environment

A source environment refers to a logical grouping of Amazon VPCs, subnets, security groups, and other infrastructure components required to run your application.

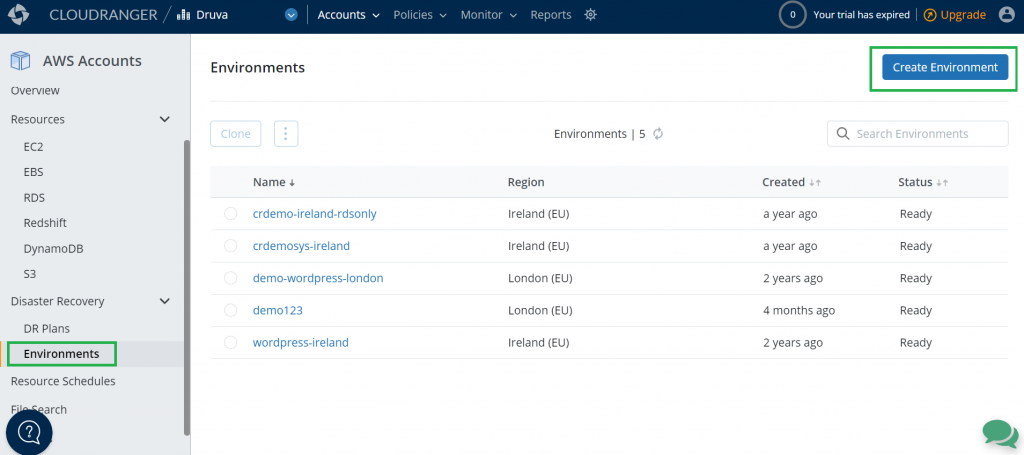
Figure 3. Create a source environment

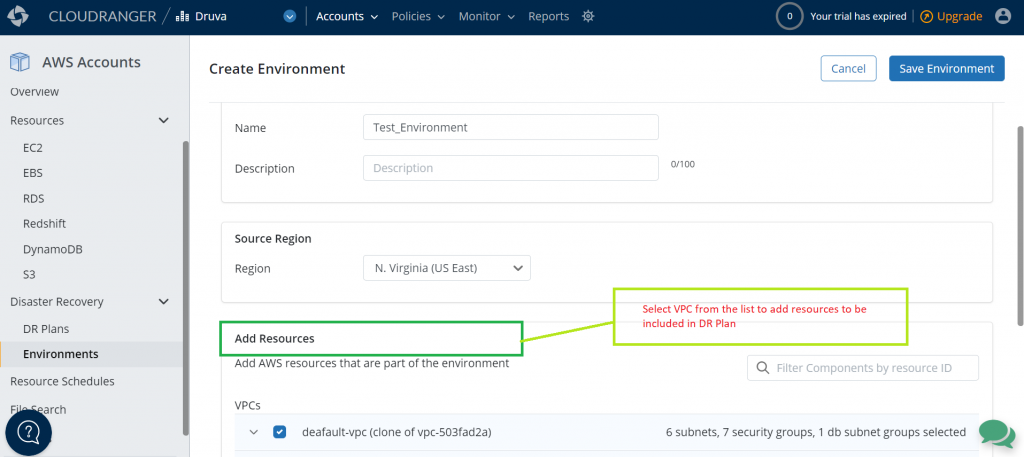
In this step, create your source environment by selecting the appropriate AWS resources you’d like to set up for failover. Druva currently supports Amazon EC2 and Amazon RDS as sources that can be protected. With Druva’s automated DR, you can failover these resources to a secondary site with the press of a button.

Figure 4. Add resources to a source environment

Note that creating a source environment does not create or update existing resources or configurations in your AWS account. It only saves this configuration information with Druva’s service.

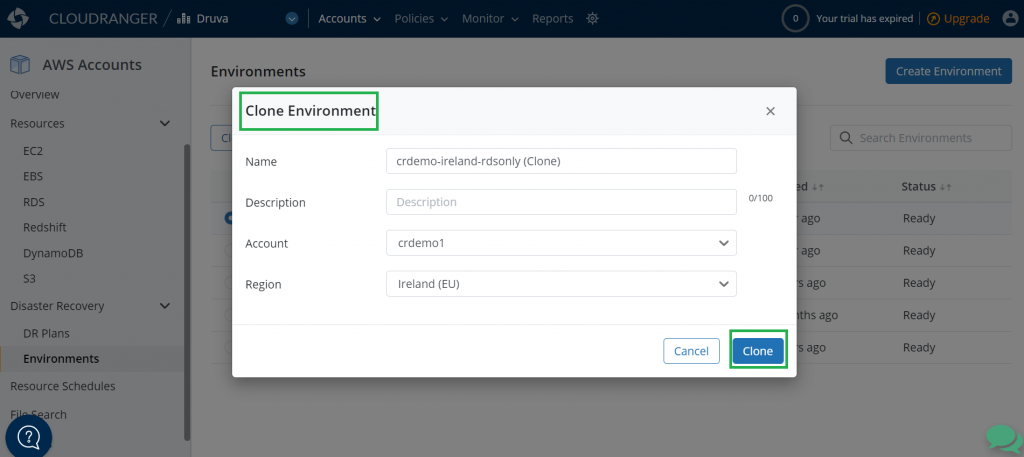
Step 3: Clone the environment

The next step is to clone the source environment to a Region where you want to failover in case of a disaster. Druva supports cloning the source environment to another Region or AWS account that you have selected. Cloning essentially replicates the source infrastructure in the target Region or account, which allows the resources to be failed over quickly and seamlessly.

Figure 5. Clone the source environment

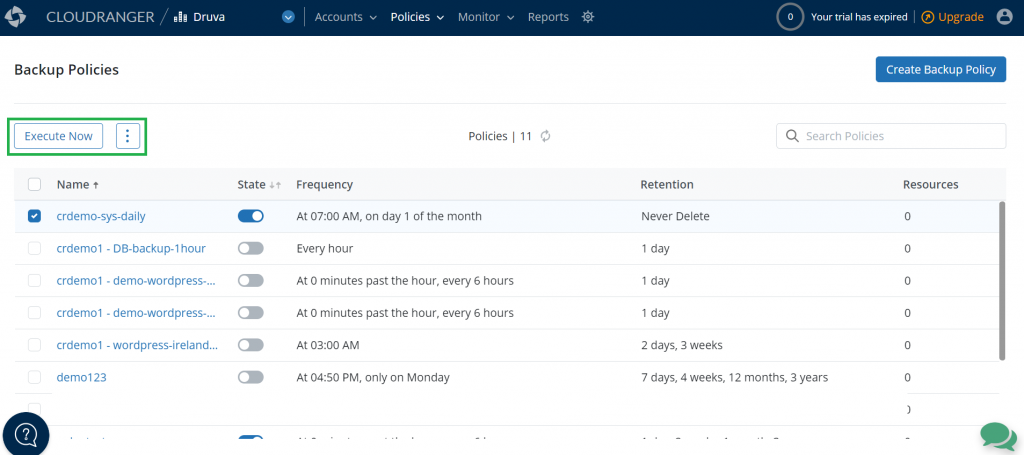
Step 4: Set up a backup policy

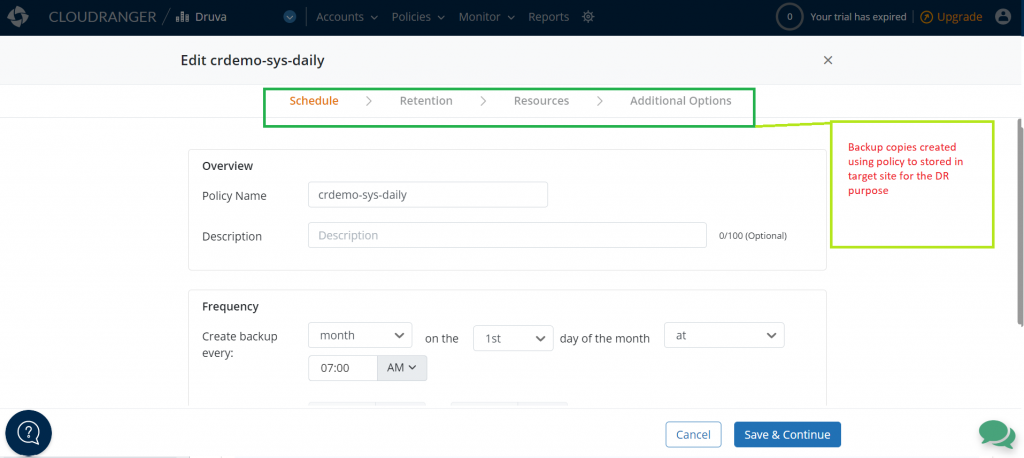
You can create a new backup policy or use an existing backup policy to create backups in the cloned or target Region. This enables Druva to restore instances using the backup copies.

Figure 6. Create a new backup policy or use an existing backup policy

Figure 7. Customize the frequency of backup schedules

Step 5: Create the DR plan

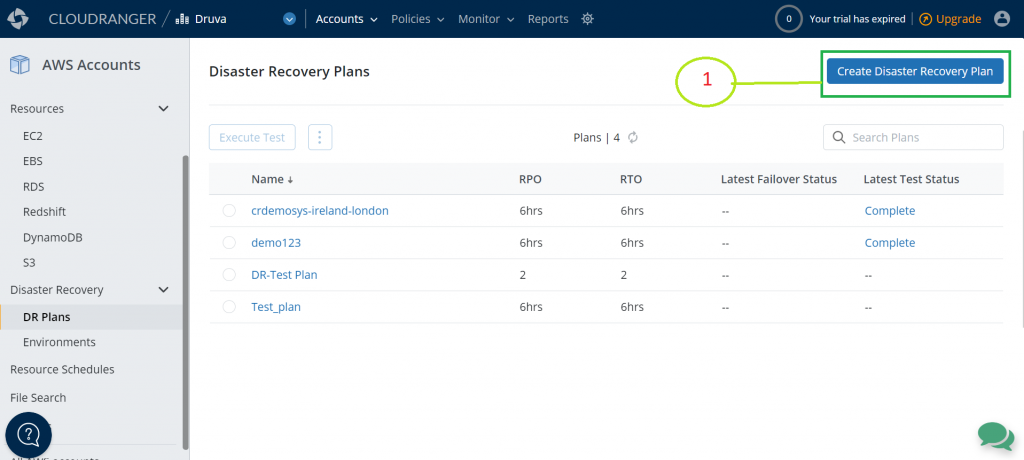
A DR plan is a structured set of instructions designed to recover resources in the event of a failure or disaster. DR aims to get you back to the production-ready setup with minimal downtime. Follow these steps to create your DR plan.

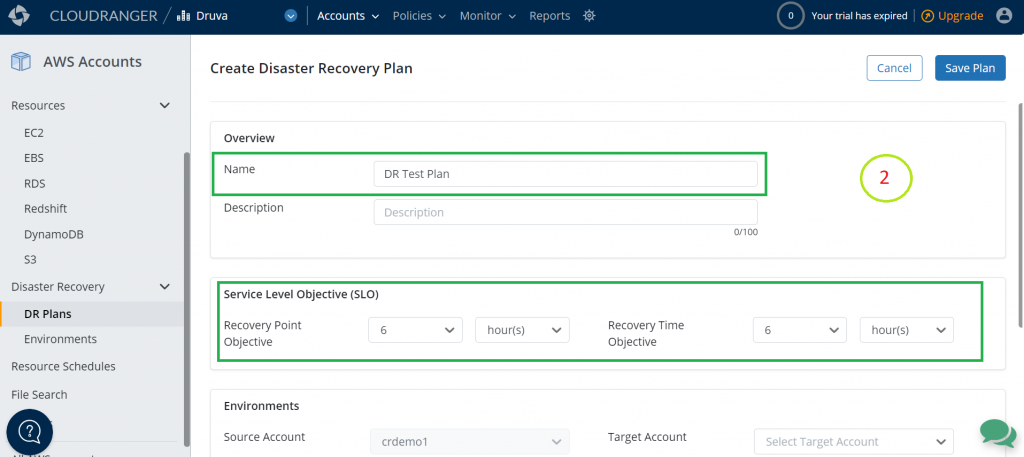
  1. Create DR Plan: Press Create Disaster Recovery Plan button to open the DR plan creation page.

Figure 8. Create a disaster recovery plan

  1. Name: Enter the name of the DR plan.
    Service Level Objective (SLO): Enter your RPO and RTO.
    • Recovery Point Objective – Example: If you set your RPO as 24 hours, and your backup was scheduled daily at 8:00 PM, but a disaster occurred at 7:59 PM, you would be able to recover data that was backed up on the previous day at 8:00 PM. You would lose the data generated after the last backup (24 hours of data loss).
    • Recovery Time Objective – Example: If you set your RTO as 30 hours, when a disaster occurred, you would be able to recover all critical IT services within 30 hours from the point in time the disaster occurs.

Figure 9. Add your RTO and RPO requirements

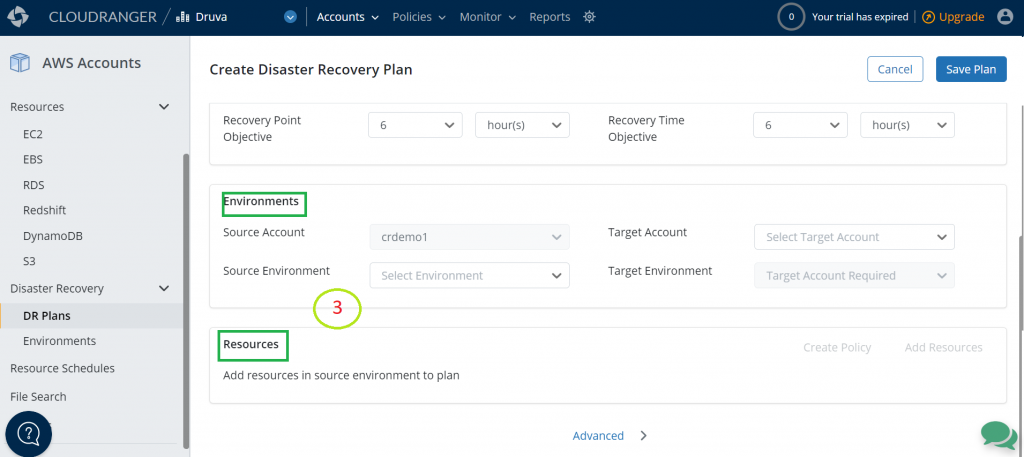
  1. Create your plan based off the source environment, target environment, and resources.
Environments
Source Account By default, this is the Druva account in which you are currently creating the DR plan.
Source Environment Select the source environment applicable within the Source Account (your Druva account in which you’re creating the DR plan).
Target Account Select the same or a different target account.
Target Environment Select the Target Environment, applicable within the Target Account.
Resources
Create Policy If you do not have a backup policy, then you can create one.
Add Resources Add resources from the source environment that you want to restore. Make sure the verification column shows a ‘Valid Backup Policy’ status. This ensures that the backup policy is frequently creating copies as per the RPO defined previously.

Figure 10. Create DR plan based off the source environment, target environment, and resources

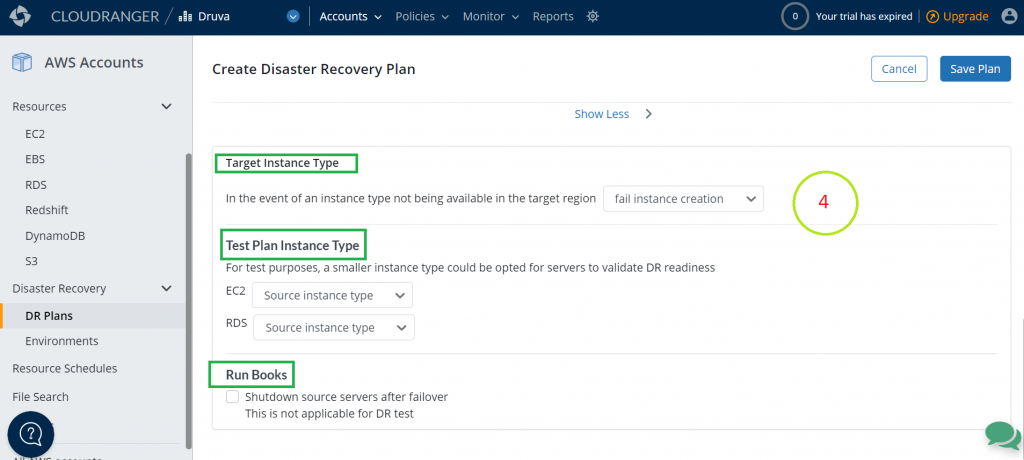
  1. Identify target instance type, test plan instance type, and run books for this DR plan.
Target Instance Type Target Instance Type can be selected. If instance type is not selected then:

  • Select an instance type which is large in size.
  • Select an instance type which is smaller.
  • Fail the creation of the instance.
Test Plan Instance Type There are many options. To reduce incurring cost, the lower instance type can be selected from all available AWS instance types.
Run Books Select this option if you would like to shutdown the source server after failover occurs.

Figure 11. Identify target instance type, test plan instance type, and run books

Step 6: Test the DR plan

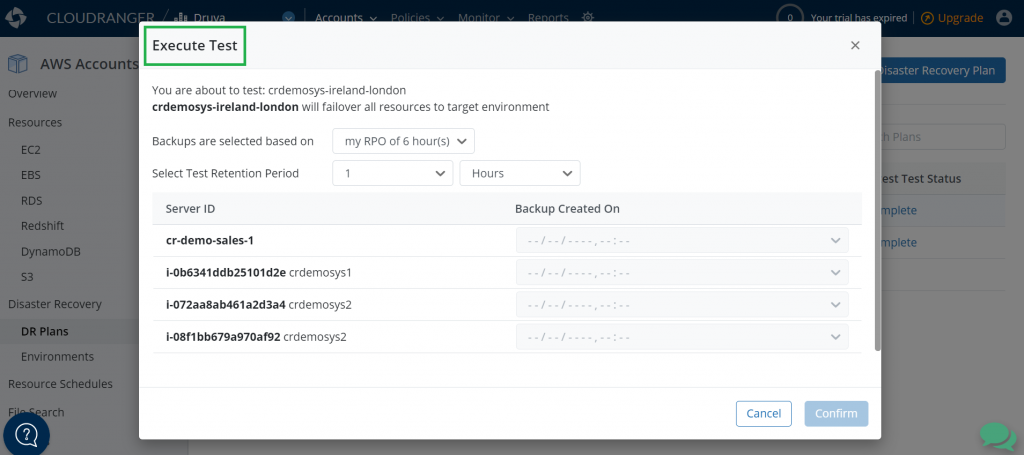
After you have defined your DR plan, it is time to test it so that you can—when necessary—initiate a failover of resources to the target Region. You can now easily try this on the resources in the cloned environment without affecting your production environment.

Figure 12. Test the DR plan

Testing your DR plan will help you to find answers for some of the questions like: How long did the recovery take? Did I meet my RTO and RPO objectives?

Step 7: Initiate the DR plan

After you have successfully tested the DR plan, it can easily be initiated with the click of a button to failover your resources from the source Region or account to the target Region or account.

Conclusion

With the growth of cloud-based services, businesses need to ensure that mission-critical applications that power their businesses are always available. Any loss of service has a direct impact on the bottom line, which makes business continuity planning a critical element to any organization. Druva offers a simple DR solution which will help you keep your business always available.

Druva provides unified backup and cloud DR with no need to manage hardware, software, or costs and complexity. It helps automate DR processes to ensure your teams are prepared for any potential disasters while meeting compliance and auditing requirements.

With Druva, you can easily validate your RTO and RPO with automated regular DR testing, cross-account DR for protection against attacks and accidental deletions, and ensure backups are isolated from your primary production account for DR planning. With cross-Region DR, you can duplicate the entire Amazon VPC environment across Regions to protect you against Regionwide failures. In conclusion, Druva is a complete solution built with a goal to protect your native AWS workloads from any disasters.

To learn more, visit: https://www.druva.com/use-cases/aws-cloud-backup/

Field Notes provides hands-on technical guidance from AWS Solutions Architects, consultants, and technical account managers, based on their experiences in the field solving real-world business problems for customers.
Akshay Panchmukh

Akshay Panchmukh

Akshay Panchmukh is the Product Manager focusing on cloud-native workloads at Druva. He loves solving complex problems for customers and helping them achieve their business goals. He leverages his SaaS product and design thinking experience to help enterprises build a complete data protection solution. He works combining the best of technology, data, product, empathy, and design to execute a successful product vision.

Scaling Data Analytics Containers with Event-based Lambda Functions

Post Syndicated from Brian Maguire original https://aws.amazon.com/blogs/architecture/scaling-data-analytics-containers-with-event-based-lambda-functions/

The marketing industry collects and uses data from various stages of the customer journey. When they analyze this data, they establish metrics and develop actionable insights that are then used to invest in customers and generate revenue.

If you’re a data scientist or developer in the marketing industry, you likely often use containers for services like collecting and preparing data, developing machine learning models, and performing statistical analysis. Because the types and amount of marketing data collected are quickly increasing, you’ll need a solution to manage the scale, costs, and number of required data analytics integrations.

In this post, we provide a solution that can perform and scale with dynamic traffic and is cost optimized for on-demand consumption. It uses synchronous container-based data science applications that are deployed with asynchronous container-based architectures on AWS Lambda. This serverless architecture automates data analytics workflows utilizing event-based prompts.

Synchronous container applications

Data science applications are often deployed to dedicated container instances, and their requests are routed by an Amazon API Gateway or load balancer. Typically, an Amazon API Gateway routes HTTP requests as synchronous invocations to instance-based container hosts.

The target of the requests is a container-based application running a machine learning service (SciLearn). The service container is configured with the required dependency packages such as scikit-learn, pandas, NumPy, and SciPy.

Containers are commonly deployed on different targets such as on-premises, Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Compute Cloud (Amazon EC2), and AWS Elastic Beanstalk. These services run synchronously and scale through Amazon Auto Scaling groups and a time-based consumption pricing model.

Figure 1. Synchronous container applications diagram

Figure 1. Synchronous container applications diagram

Challenges with synchronous architectures

When using a synchronous architecture, you will likely encounter some challenges related to scale, performance, and cost:

  • Operation blocking. The sender does not proceed until Lambda returns, and failure processing, such as retries, must be handled by the sender.
  • No native AWS service integrations. You cannot use several native integrations with other AWS services such as Amazon Simple Storage Service (Amazon S3), Amazon EventBridge, and Amazon Simple Queue Service (Amazon SQS).
  • Increased expense. A 24/7 environment can result in increased expenses if resources are idle, not sized appropriately, and cannot automatically scale.

The New for AWS Lambda – Container Image Support blog post offers a serverless, event-based architecture to address these challenges. This approach is explained in detail in the following section.

Benefits of using Lambda Container Image Support

In our solution, we refactored the synchronous SciLearn application that was deployed on instance-based hosts as an asynchronous event-based application running on Lambda. This solution includes the following benefits:

  • Easier dependency management with Dockerfile. Dockerfile allows you to install native operating system packages and language-compatible dependencies or use enterprise-ready container images.
  • Similar tooling. The asynchronous and synchronous solutions use Amazon Elastic Container Registry (Amazon ECR) to store application artifacts. Therefore, they have the same build and deployment pipeline tools to inspect Dockerfiles. This means your team will likely spend less time and effort learning how to use a new tool.
  • Performance and cost. Lambda provides sub-second autoscaling that’s aligned with demand. This results in higher availability, lower operational overhead, and cost efficiency.
  • Integrations. AWS provides more than 200 service integrations to deploy functions as container images on Lambda, without having to develop it yourself so it can be deployed faster.
  • Larger application artifact up to 10 GB. This includes larger application dependency support, giving you more room to host your files and packages in oppose to hard limit of 250 MB of unzipped files for deployment packages.

Scaling with asynchronous events

AWS offers two ways to asynchronously scale processing independently and automatically: Elastic Beanstalk worker environments and asynchronous invocation with Lambda. Both options offer the following:

  • They put events in an SQS queue.
  • They can be designed to take items from the queue only when they have the capacity available to process a task. This prevents them from becoming overwhelmed.
  • They offload tasks from one component of your application by sending them to a queue and process them asynchronously.

These asynchronous invocations add default, tunable failure processing and retry mechanisms through “on failure” and “on success” event destinations, as described in the following section.

Integrations with multiple destinations

“On failure” and “on success” events can be logged in an SQS queue, Amazon Simple Notification Service (Amazon SNS) topic, EventBridge event bus, or another Lambda function. All four are integrated with most AWS services.

“On failure” events are sent to an SQS dead-letter queue because they cannot be delivered to their destination queues. They will be reprocessed them as needed, and any problems with message processing will be isolated.

Figure 2 shows an asynchronous Amazon API Gateway that has placed an HTTP request as a message in an SQS queue, thus decoupling the components.

The messages within the SQS queue then prompt a Lambda function. This runs the machine learning service SciLearn container in Lambda for data analysis workflows, which are integrated with another SQS dead letter queue for failures processing.

Figure 2. Example asynchronous-based container applications diagram

Figure 2. Example asynchronous-based container applications diagram

When you deploy Lambda functions as container images, they benefit from the same operational simplicity, automatic scaling, high availability, and native integrations. This makes it an appealing architecture for our data analytics use cases.

Design considerations

The following can be considered when implementing Docker Container Images with Lambda:

  • Lambda supports container images that have manifest files that follow these formats:
    • Docker image manifest V2, schema 2 (Docker version 1.10 and newer)
    • Open Container Initiative (OCI) specifications (v1.0.0 and up)
  • Storage in Lambda:
  • On create/update, Lambda will cache the image to speed up the cold start of functions during execution. Cold starts occur on an initial request to Lambda, which can lead to longer startup times. The first request will maintain an instance of the function for only a short time period. If Lambda has not been called during that period, the next invocation will create a new instance
  • Fine grain role policies are highly recommended for security purposes
  • Container images can use the Lambda Extensions API to integrate monitoring, security and other tools with the Lambda execution environment.

Conclusion

We were able to architect this synchronous service based on a previously deployed on instance-based hosts and design it to become asynchronous on Amazon Lambda.

By using the new support for container-based images in Lambda and converting our workload into an asynchronous event-based architecture, we were able to overcome these challenges:

  • Performance and security. With batch requests, you can scale asynchronous workloads and handle failure records using SQS Dead Letter Queues and Lambda destinations. Using Lambda to integrate with other services (such as EventBridge and SQS) and using Lambda roles simplifies maintaining a granular permission structure. When Lambda uses an Amazon SQS queue as an event source, it can scale up to 60 more instances per minute, with a maximum of 1,000 concurrent invocations.
  • Cost optimization. Compute resources are a critical component of any application architecture. Overprovisioning computing resources and operating idle resources can lead to higher costs. Because Lambda is serverless, it only incurs costs on when you invoke a function and the resources allocated for each request.

Use IAM Access Analyzer to generate IAM policies based on access activity found in your organization trail

Post Syndicated from Mathangi Ramesh original https://aws.amazon.com/blogs/security/use-iam-access-analyzer-to-generate-iam-policies-based-on-access-activity-found-in-your-organization-trail/

In April 2021, AWS Identity and Access Management (IAM) Access Analyzer added policy generation to help you create fine-grained policies based on AWS CloudTrail activity stored within your account. Now, we’re extending policy generation to enable you to generate policies based on access activity stored in a designated account. For example, you can use AWS Organizations to define a uniform event logging strategy for your organization and store all CloudTrail logs in your management account to streamline governance activities. You can use Access Analyzer to review access activity stored in your designated account and generate a fine-grained IAM policy in your member accounts. This helps you to create policies that provide only the required permissions for your workloads.

Customers that use a multi-account strategy consolidate all access activity information in a designated account to simplify monitoring activities. By using AWS Organizations, you can create a trail that will log events for all Amazon Web Services (AWS) accounts into a single management account to help streamline governance activities. This is sometimes referred to as an organization trail. You can learn more from Creating a trail for an organization. With this launch, you can use Access Analyzer to generate fine-grained policies in your member account and grant just the required permissions to your IAM roles and users based on access activity stored in your organization trail.

When you request a policy, Access Analyzer analyzes your activity in CloudTrail logs and generates a policy based on that activity. The generated policy grants only the required permissions for your workloads and makes it easier for you to implement least privilege permissions. In this blog post, I’ll explain how to set up the permissions for Access Analyzer to access your organization trail and analyze activity to generate a policy. To generate a policy in your member account, you need to grant Access Analyzer limited cross-account access to access the Amazon Simple Storage Service (Amazon S3) bucket where logs are stored and review access activity.

Generate a policy for a role based on its access activity in the organization trail

In this example, you will set fine-grained permissions for a role used in a development account. The example assumes that your company uses Organizations and maintains an organization trail that logs all events for all AWS accounts in the organization. The logs are stored in an S3 bucket in the management account. You can use Access Analyzer to generate a policy based on the actions required by the role. To use Access Analyzer, you must first update the permissions on the S3 bucket where the CloudTrail logs are stored, to grant access to Access Analyzer.

To grant permissions for Access Analyzer to access and review centrally stored logs and generate policies

  1. Sign in to the AWS Management Console using your management account and go to S3 settings.
  2. Select the bucket where the logs from the organization trail are stored.
  3. Change object ownership to bucket owner preferred. To generate a policy, all of the objects in the bucket must be owned by the bucket owner.
  4. Update the bucket policy to grant cross-account access to Access Analyzer by adding the following statement to the bucket policy. This grants Access Analyzer limited access to the CloudTrail data. Replace the <organization-bucket-name>, and <organization-id> with your values and then save the policy.
    {
        "Version": "2012-10-17",
        "Statement": 
        [
        {
            "Sid": "PolicyGenerationPermissions",
            "Effect": "Allow",
            "Principal": {
                "AWS": "*"
            },
            "Action": [
                "s3:GetObject",
                "s3:ListBucket"
            ],
            "Resource": [
                "arn:aws:s3:::<organization-bucket-name>",
                "arn:aws:s3:::my-organization-bucket/AWSLogs/o-exampleorgid/${aws:PrincipalAccount}/*
    "
            ],
            "Condition": {
    "StringEquals":{
    "aws:PrincipalOrgID":"<organization-id>"
    },
    
                "StringLike": {"aws:PrincipalArn":"arn:aws:iam::${aws:PrincipalAccount}:role/service-role/AccessAnalyzerMonitorServiceRole*"            }
            }
        }
        ]
    }
    

By using the preceding statement, you’re allowing listbucket and getobject for the bucket my-organization-bucket-name if the role accessing it belongs to an account in your Organizations and has a name that starts with AccessAnalyzerMonitorServiceRole. Using aws:PrincipalAccount in the resource section of the statement allows the role to retrieve only the CloudTrail logs belonging to its own account. If you are encrypting your logs, update your AWS Key Management Service (AWS KMS) key policy to grant Access Analyzer access to use your key.

Now that you’ve set the required permissions, you can use the development account and the following steps to generate a policy.

To generate a policy in the AWS Management Console

  1. Use your development account to open the IAM Console, and then in the navigation pane choose Roles.
  2. Select a role to analyze. This example uses AWS_Test_Role.
  3. Under Generate policy based on CloudTrail events, choose Generate policy, as shown in Figure 1.
     
    Figure 1: Generate policy from the role detail page

    Figure 1: Generate policy from the role detail page

  4. In the Generate policy page, select the time window for which IAM Access Analyzer will review the CloudTrail logs to create the policy. In this example, specific dates are chosen, as shown in Figure 2.
     
    Figure 2: Specify the time period

    Figure 2: Specify the time period

  5. Under CloudTrail access, select the organization trail you want to use as shown in Figure 3.

    Note: If you’re using this feature for the first time: select create a new service role, and then choose Generate policy.

    This example uses an existing service role “AccessAnalyzerMonitorServiceRole_MBYF6V8AIK.”
     

    Figure 3: CloudTrail access

    Figure 3: CloudTrail access

  6. After the policy is ready, you’ll see a notification on the role page. To review the permissions, choose View generated policy, as shown in Figure 4.
     
    Figure 4: Policy generation progress

    Figure 4: Policy generation progress

After the policy is generated, you can see a summary of the services and associated actions in the generated policy. You can customize it by reviewing the services used and selecting additional required actions from the drop down. To refine permissions further, you can replace the resource-level placeholders in the policies to restrict permissions to just the required access. You can learn more about granting fine-grained permissions and creating the policy as described in this blog post.

Conclusion

Access Analyzer makes it easier to grant fine-grained permissions to your IAM roles and users by generating IAM policies based on the CloudTrail activity centrally stored in a designated account such as your AWS Organizations management accounts. To learn more about how to generate a policy, see Generate policies based on access activity in the IAM User Guide.

If you have feedback about this blog post, submit comments in the Comments section below. If you have questions about this blog post, start a new thread on the IAM forum or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Mathangi Ramesh

Mathangi Ramesh

Mathangi is the product manager for AWS Identity and Access Management. She enjoys talking to customers and working with data to solve problems. Outside of work, Mathangi is a fitness enthusiast and a Bharatanatyam dancer. She holds an MBA degree from Carnegie Mellon University.

Apply the principle of separation of duties to shell access to your EC2 instances

Post Syndicated from Vesselin Tzvetkov original https://aws.amazon.com/blogs/security/apply-the-principle-of-separation-of-duties-to-shell-access-to-your-ec2-instances/

In this blog post, we will show you how you can use AWS Systems Manager Change Manager to control access to Amazon Elastic Compute Cloud (Amazon EC2) instance interactive shell sessions, to enforce separation of duties. Separation of duties is a design principle where more than one person’s approval is required to conclude a critical task, and it is an important part of the AWS Well-Architected Framework. You will be using AWS Systems Manager Session Manager in this post to start a shell session in managed EC2 instances.

To get approval, the operator requests permissions by creating a change request for a shell session to an EC2 instance. An approver reviews and approves the change request. The approver and requestor cannot be the same Identity and Access Management (IAM) principal. Upon approval, an AWS Systems Manager Automation runbook is started. The Automation runbook adds a tag to the operator’s IAM principal that allows it to start a shell in the specified targets. By default, the operator needs to start the session within 10 minutes of approval (although the validity period is configurable). After the 10 minutes elapse, the Automation runbook removes the tag from the principal, which means that the permissions to start new sessions are revoked.

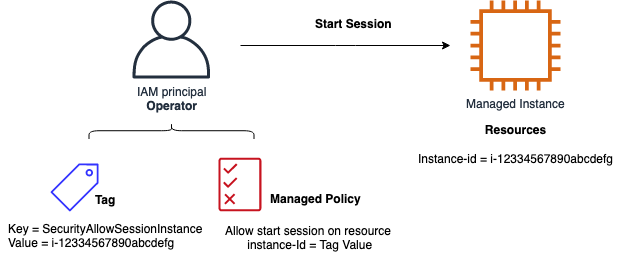
To implement the solution described in this post, you use attribute-based access control (ABAC) based policy. In order to start a Systems Manager session, the operator’s IAM principal must have the tag key SecurityAllowSessionInstance, and the tag value set to the target EC2 instance ID. All operator principals have attached the same managed policy, which allows the session to start only if the tag is present and the value is equal to the instance ID. Figure 1 shows an example in which the IAM principal tag SecurityAllowSessionInstance has the value i-1234567890abcdefg, which is the same as the instance ID.

Figure 1: Tag and managed policy pattern

Figure 1: Tag and managed policy pattern

In this post, we will take you through the following steps:

  1. Review the architecture of the solution. (See the Architecture section.)
  2. Set up Systems Manager and Change Manager in the console.
  3. Deploy an AWS CloudFormation template that will provision the following:
    • A change management template AllowSsmSessionStartTemplate to request permission for a Session Manager shell session on a specified EC2 instance.
    • The Systems Manager Automation runbook with three steps that: adds a tag to the principal; waits 10 minutes (configurable); and removes the tag. The tag key is SecurityAllowSessionInstance.
    • An IAM managed policy to be added to an IAM principal, which allows starting a Systems Manager session only if the tag AllowStartSsmSessionBasedOnIamTags is present.
    • An Amazon SNS topic change-manager-ssm-approval where approvers can get notification about requests.
    • An IAM role named SsmSessionControlChangeMangerRole, to be used for the Systems Manager Automation runbook.

    Note: Before you use the change template, you will approve the change management template in the AWS Management Console (one time).

  4. Perform simple test cases to demonstrate how an operator can obtain permission and start a session in a managed instance.
  5. Perform status monitoring.

You can use this solution across your AWS Organizations to give you the benefit of centrally managing change-related tasks in one member account, which you specify to be the delegated administrator account. For more information about how to set this up, see Setting up Change Manager for an organization.

Note: The operator can have multiple sessions in different EC2 instances simultaneously, but the sessions must be approved and started one after another because of tag overwrite on approval.

For more information about change management actions, including approvals and starting the runbook, see Auditing and logging Change Manager activity in the AWS Systems Manager User Guide.

Architecture

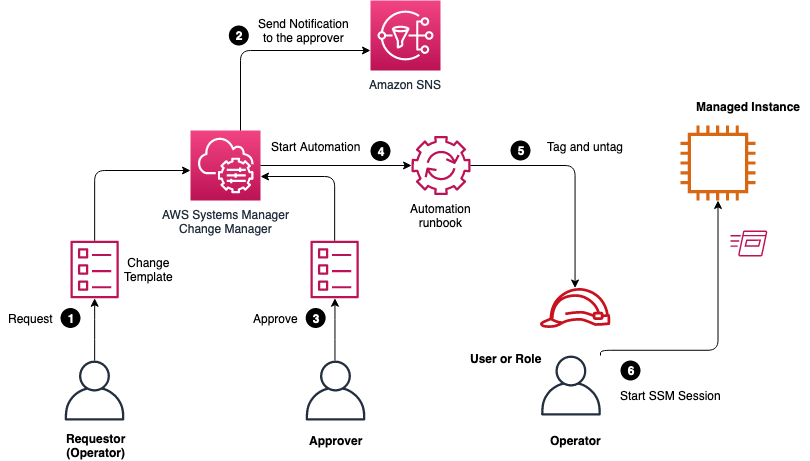
The architecture of this solution is shown in Figure 2.

Figure 2: Solution architecture

Figure 2: Solution architecture

The main steps shown in Figure 2 are the following:

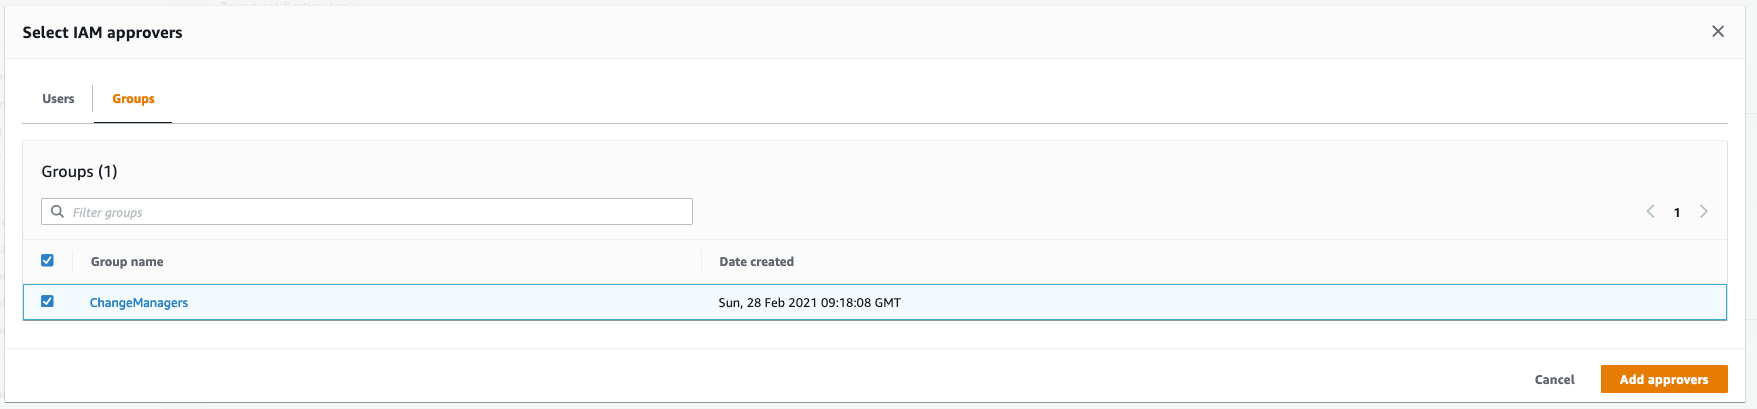
  1. Request: The requestor (which can be the operator) creates a change request in Systems Manager Change Manager and selects the template AllowSsmSessionStartTemplate. You need to provide the following mandatory parameters: name of change, approvals (users, group, or roles), IAM role for the execution of change, target account, EC2 instance ID, operator’s principal type (user or role), and operator’s principal name.
  2. Send notification: The notification is sent to the Amazon SNS topic change-manager-ssm-approval for the new change request.
  3. Approve: The approver reviews and approves the request.
  4. Start automation: The Automation runbook AllowStartSsmSession is started at the time specified in the change request.
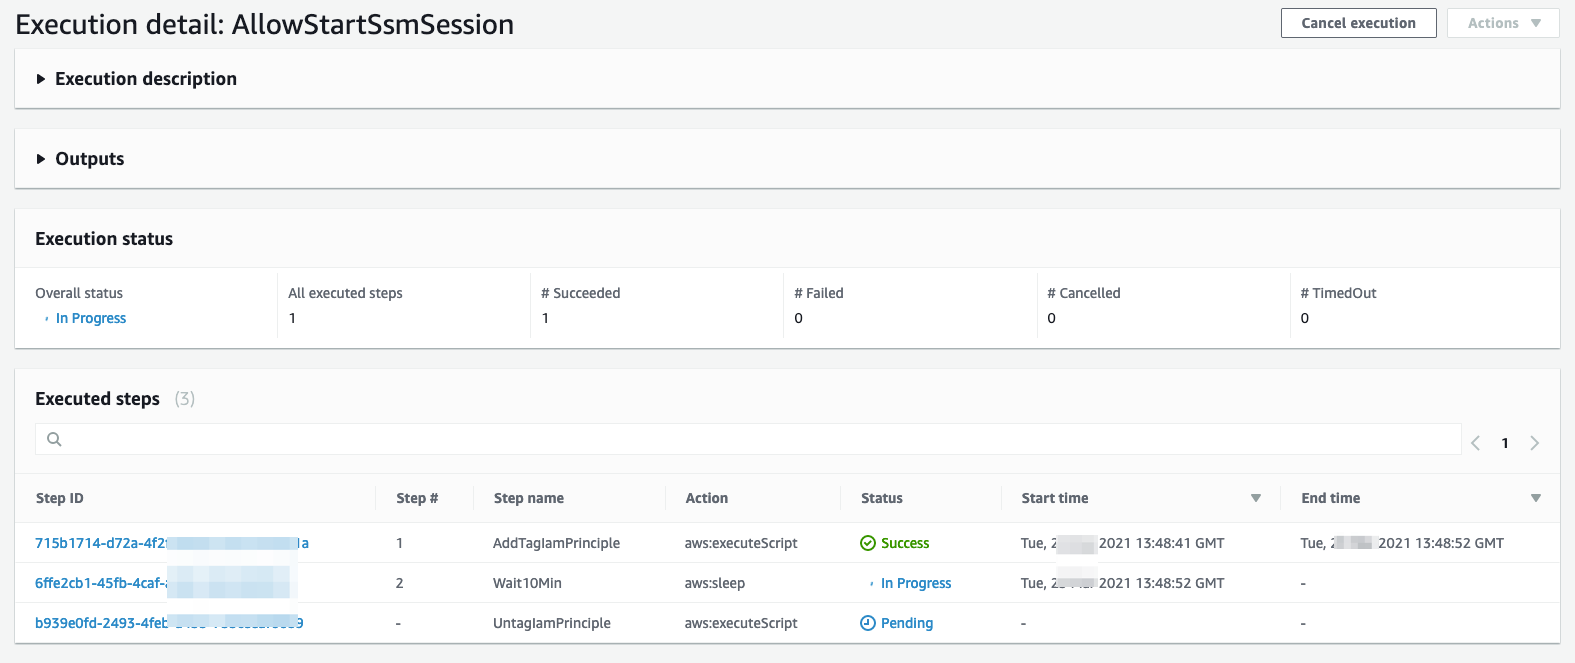
  5. Tag: The operator’s IAM principal is tagged with the key SecurityAllowSessionInstance. After 10 minutes, the runbook completes by removing the tag from the IAM principal.
  6. Start session: The operator can start a session to the instance by using Systems Manager Session Manager within 10 minutes of approval. A notification is sent to the SNS topic change-manager-ssm-approval, where the operator can also subscribe to be notified.

Roles and permissions

The provided managed policy AllowStartSsmSessionBasedOnIamTags gives permission to start the Systems Manager session when the instance ID is equal to principal tag, and additionally to terminate the session. The managed policy allows the operator to keep an already active session beyond the approval interval and terminate it as preferred. Resumption of the session is not supported, and the operator will need to start a new session instead.

WARNING: You should validate that the operator principal (which is an IAM user or role) does not have permissions on the actions ssm:StartSession, ssm:TerminateSession, ssm:ResumeSession outside the managed policy used in this solution.

WARNING: It is very important that the operator must not have permission to change the relevant IAM roles, users, policies, or principal tags, so that the operator cannot bypass the approval process.

Set up Systems Manager and Change Manager

You need to initially activate Systems Manager and Systems Manager Change Manager in your account. If you have already activated them, you can skip this section.

Note: You should enable Systems Manager as described in Setting up AWS Systems Manager, according to your company needs. The minimal requirement is to set up the service-linked role AWSServiceRoleForAmazonSSM that will be used by Systems Manager.

To create the service-linked IAM role

  1. Open the IAM console. In the navigation pane, choose Roles, then choose Create role.
  2. For the AWS Service role type, choose Systems Manager.
  3. Choose the use case Systems Manager – Inventory and Maintenance Windows, then choose Next: Permissions.
  4. Keep all default values, choose Next: Tags, and then choose Next: Review.
  5. Review the role and then choose Create role.

For more information, see Creating a service-linked role for Systems Manager.

Next, you set up Systems Manager Change Manager as described in Setting up Change Manager. Your specifics will vary depending on whether you use AWS Organizations or a single account.

Define the IAM users or groups that are allowed to approve change templates

Every change template should be approved before use (optional). The approval can be done by users and groups. If you use IAM roles in your organization, you will need a temporary user, which you can set up as described in Creating IAM users (console). Alternatively, you can use the change templates without explicit approval, as described later in this section.

To add reviewers for change templates

  1. In the AWS Systems Manager console, choose Change Manager, choose Settings, then choose Template reviewers.
  2. On the Select IAM approvers page, review the Users tab and Groups tab, as shown in Figure 3, and add approvers if necessary.


Figure 3: Change Manger settings

Figure 3: Change Manger settings

If you prefer not to explicitly review and approve the change template before use, you must turn off approval as follows.

To turn off approval of change templates before use

  1. In the Systems Manager console, choose Change Manager, then choose Settings.
  2. Under Best practices, set the option Require template review and approval before use to disabled.

Deploy the solution

After you complete the setup, you will perform the following steps one time in your selected account and AWS Region. The solution manages the permissions in all Regions you select, because IAM roles and policies are global entities.

To launch the stack

  1. Choose the following Launch Stack button to open the AWS CloudFormation console pre-loaded with the template. You must sign in to your AWS account in order to launch the stack in the required Region.
    Select the Launch Stack button to launch the template
  2. On the CloudFormation launch panel, specify the parameter Approval validity in minutes to correspond to your company policy, or keep the default value of 10 minutes.

(Optional) To approve the template

  1. To request approval of the Change Manager template, in the Systems Manager console, choose Change Manager, and then choose Change templates. Select AllowSsmSessionStartTemplate and submit for approval.
  2. To approve the Change Manager template, sign in to the Systems Manager console as the required approver user or group. Choose Change Manager, and then choose Change templates. Select AllowSsmSessionStartTemplate and choose Actions, Approve template. For more information, see Reviewing and approving or rejecting change templates.
  3. (Optional) The Systems Manager session approvers should subscribe to the SNS topic change-manager-ssm-approval, to get notification on new requests.

Now you’re ready to use the solution.

Test the solution

Next, we’ll demonstrate how you can test the solution end-to-end by doing the following: creating two IAM roles (Operator and Approver), launching an EC2 instance, requesting access by Operator to the instance, approving the request by Approver, and finally starting a Systems Manager session on the EC2 instance by Operator. You will run the test in the single account where you deployed the solution. We assume that you have set up Systems Manager as described in the Set up Systems Manager and Change Manager section.

Note: If you’re not using IAM roles in your organization, you can use IAM users instead, as described in Creating IAM users (console).

To prepare to test the solution

  1. Open the IAM console and create an IAM role named Operator in your account, and attach the following managed policies: ReadOnlyAccess (AWS managed) and AllowStartSsmSessionBasedOnIamTags (which you created in this post). For more information, see Creating IAM roles
  2. Create a second IAM role named Approver in your account, and attach the following AWS managed policies: ReadOnlyAccess and AmazonSSMFullAccess.
  3. Create an IAM role named EC2Role with a trust policy to the EC2 service (ec2.amazonaws.com) and attach the AWS managed policy AmazonEC2RoleforSSM. Alternatively, you can confirm that your existing EC2 instances have the AmazonEC2RoleforSSM policy attached to their role. For more information, see Creating a role for an AWS service (console).
  4. Open the Amazon EC2 console and start a test EC2 instance of type Amazon Linux 2 with the IAM role EC2Role that you created in step 3. You can keep the default values for all the other parameters. You don’t need to set up VPC Security Group rules to allow inbound SSH to the EC2 instance. Take note of the instance-id, because you will need it later. For more information, see Launch an Amazon EC2 Instance.
  5. Open the Amazon SNS console. Under Simple Notification Service, for Topics, subscribe to the SNS topic change-manager-ssm-approval. For more information, see Subscribing to an Amazon SNS topic.

To do a positive test of the solution

  1. Open the Systems Manager console, sign in as Operator, choose Change Manager, and create a change request.
  2. Select the template AllowSsmSessionStartTemplate.
  3. On the Specify change details page, enter a name and description, and select the IAM role Approver as approver.
  4. For Target notification topic, select the SNS topic change-manager-ssm-approval, as shown in Figure 4. Choose Next.

    Figure 4: Creating a change request

    Figure 4: Creating a change request

  5. On the Specify parameters page, provide the automation IAM role SsmSessionControlChangeMangerRole, the instance-id you noted earlier, the principal name Operator, and the principal type role, as shown in Figure 5.

    Figure 5: Specify parameters for the change request

    Figure 5: Specify parameters for the change request

  6. Next, sign in as Approver. In the Systems Manager console, choose Change Manager.
  7. On the Requests tab, as shown in Figure 6, select the request and choose Approve. (For more information, see Reviewing and approving or rejecting change requests (console).) The Automation runbook will be started.

    Figure 6: Change Manager overview

    Figure 6: Change Manager overview

  8. Sign in as Operator. Within the approval validity time that you provided in the template (10 minutes is the default), connect to the instance by using Systems Manager as described in Start a session.When the session has started and you see Unix shell at the instance, the positive test is done.

Next, you can do a negative test, to demonstrate that access isn’t possible after the approval validity period (10 minutes) has elapsed.

To do a negative test of the solution

  1. Do steps 1 through 7 of the previous procedure, if you haven’t already done so.
  2. Sign in as IAM role Operator. Wait several minutes longer than the approval validity time (10-minute default) and connect to the instance by using Systems Manager as described in Start a session.You will see that the IAM role Operator doesn’t have permission to start a session.

Clean up the resources

After the tests are finished, terminate the EC2 instance to avoid incurring future costs and remove the roles if these are no longer needed.

Status monitoring

In the Systems Manager console, on the Change Manager page, on the Requests tab, you can find all service requests and their status, and a link to the log of the runbook, as shown in Figure 7.

Figure 7: Change Manger runbook log

Figure 7: Change Manger runbook log

In the example shown in Figure 7, you can see the status of the following steps in the Automation runbook: tagging the principal, waiting, and removing the principal tag. For more information about audit and login, see Auditing and logging Change Manager activity.

Conclusion

In this post, you‘ve learned how you can enforce separation of duties by using an approval workflow in AWS Systems Manager Change Manager. You can also extend this pattern to use it with AWS Organizations, as described in Setting up Change Manager for an organization. For more information, see Configuring Change Manager options and best practices.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Systems Manager forum.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Vesselin Tzvetkov

Vesselin is a senior security architect at AWS Professional Services and is passionate about security architecture and engineering innovative solutions. Outside of technology, he likes classical music, philosophy, and sports. He holds a Ph.D. in security from TU-Darmstadt and a M.S. in electrical engineering from Bochum University in Germany.

Pedro Galvao

Pedro is a security engineer at AWS Professional Services. His favorite activity is to help customer doing awesome security engineering work on AWS.

How IPONWEB Adopted Spot Instances to Run their Real-time Bidding Workloads

Post Syndicated from Roman Boiko original https://aws.amazon.com/blogs/architecture/how-iponweb-adopted-spot-instances-to-run-their-real-time-bidding-workloads/

IPONWEB is a global leader that builds programmatic, real-time advertising technology and infrastructure for some of the world’s biggest digital media buyers and sellers. The core of IPONWEB’s business is Real-time Bidding (RTB). IPONWEB’s platform processes, transmits, and auctions huge volumes of bid requests and bid responses in real time. They are then able to determine the optimal ad impression to be displayed to an end user.

IPONWEB processes over 1 trillion impression auctions per month. The volumes of impressions require significant compute power to make calculations and complete the entire bidding auction within 200 milliseconds. IPONWEB’s flagship RTB products, BidSwitch and BSWX, have been running on Amazon EC2 reserved and On-Demand Instances. The nature of the workload for this volume of compute for this short a time, has been notably spiky. IPONWEB maintained a core workload running 24/7 on EC2 instances covered by Reserved Instances and Savings Plans.

To optimize costs further, IPONWEB decided to use Amazon EC2 Spot Instances. Although this decision is also advantageous for workload efficiency, adopting Spot Instances did introduce a few challenges that needed to be addressed.

Some challenges in using Spot Instances for this use case

The Real-time Bidding (RTB) workload is critical to the business. Any interruption of bid processing has a negative impact on revenue. While the spikiness issue needed to be addressed, it was imperative to find a solution that could be implemented in a smooth and seamless fashion.

Efficient distribution over Availability Zones (AZs) within the AWS Region being used was imperative. RTB auctions process trillions of requests and consume large volumes of network traffic. Consequently, IPONWEB is continuously optimizing traffic costs along with compute costs. The architectural approach is to put as much workload as possible in one AZ to reduce inter-AZ traffic. For better performance, IPONWEB’s main MongoDB database and Spot Instances are running in the same AZ.

Under certain circumstances, using Spot Instances in other AZs can still be a good choice. AWS charges for traffic between AZs, so IPONWEB defined a break point. This occurs when usage of an EC2 Spot Instance in a different AZ became equal to usage of an EC2 On-Demand Instance in the same AZ.

This break point calculation led to the following best practices (in order of most value to least, for this use case):

  1. The most efficient practice was to run Spot Instances in the same AZ as the database
  2. Next effective was to run Spot Instances in the other AZs
  3. The third option was to run On-Demand Instances in the same AZ
  4. Least effective was to run On-Demand Instances in the other AZs

IPONWEB’s solution

IPONWEB evaluated Auto Scaling groups using both Spot and On-Demand Instances. They concluded that using Auto Scaling alone would not satisfy all the requirements, and it would be difficult to distribute workloads between AZs adequately. This is because an Auto Scaling group tries to distribute the instances across all the AZs evenly. However, IPONWEB needed to scale in one AZ initially, to avoid unnecessary cross AZ traffic. In addition, one Auto Scaling group can’t compensate for the sudden termination of a large number of Spot Instances. IPONWEB created a more flexible and reliable solution based on using four Auto Scaling groups.

  1. The first Auto Scaling group runs only on Spot Instances in the same AZ as the main database application.
  2. The second Auto Scaling group is running only Spot Instances in the other AZs.
  3. The third Auto Scaling group is running EC2 On-Demand Instances in the database AZ.
  4. The fourth Auto Scaling group is for EC2 On-Demand Instance on the other AZs.

The application workload running on the instances in these four Auto Scaling groups is evenly distributed. This is done using an Application Load Balancer (ALB), or IPONWEB’s purpose-built load balancer.

Figure 1. Spot and On-Demand scaling by different AZs

Figure 1. Spot and On-Demand Instances scaling by different AZs

IPONWEB then needed to create a proper scaling policy for each Auto Scaling group. They decided to implement a self-monitoring mechanism in the application. This monitored how much compute resources (CPU and memory) are still available at any given time. Using this information, the application determines if it is able to take the next processing request. If it’s unable to, a log entry is created, and an “empty” response is returned. IPONWEB created a composite metric based on the drop rate and CPU utilization of each host.

IPONWEB used that custom metric to create scaling policies for every Auto Scaling group. Each Auto Scaling group has a specific threshold. This provides granular control, such as when, and under what conditions the particular Auto Scaling group scales-out or scales-in. It will set a lower threshold for the first Auto Scaling group and higher thresholds for the next Auto Scaling groups.

For example, the group with Spot Instances in the same AZ starts scaling at 75% utilization. The group with Spot Instances in other AZs starts scaling at 80% utilization.

  • Because each instance in every group receives the same number of incoming requests to process, the first group will be scaling earlier than the others.
  • If some Spot Instances are shut down in the first group, then the total utilization will increase, and the second group will begin scaling.
  • If there is a shortage of Spot Instances in other AZs as well, then the group with EC2 On-Demand Instances will scale out.
  • When the Spot Instances are available and can be used again, the first group will use them. Then total utilization will decrease, causing the other groups to scale in.

Typically, the majority of this workload is done by the first group. The other groups are running with a bare minimum of two instances in each. After going live with this solution, IPONWEB observed that they can usually run the major portion of their workloads with the cheapest option. In this case, it was using Spot Instances in the same AZ as their database. There were several times when a large number of the Spot Instances were shut down. When this happened, the scaling diverted to On-Demand Instances. In general, the solution worked well and there was no degradation on the running services.

Conclusion

This solution helps IPONWEB utilize compute resources more efficiently using AWS, to place and process more bids. After the migration, IPONWEB increased infrastructure on AWS by ~15% without incurring additional costs. This solution can also be used for other workloads where you must have a granular control on the scaling while minimizing the costs.

Victor Gorelik, VP of Cloud Infrastructure at IPONWEB said:

“If you use cloud without optimizations, it is expensive. There are two ways to optimize the costs – use either Savings Plans or Spot Instances. But it feels like using Savings Plans is a step back to the traditional model where you buy hardware. On the other hand, using Spots is making you more Cloud native and is the way to move forward. I believe that in the future the majority of our workloads will be run on Spot.”

Read more here:

15 years of silicon innovation with Amazon EC2

Post Syndicated from Neelay Thaker original https://aws.amazon.com/blogs/compute/15-years-of-silicon-innovation-with-amazon-ec2/

The Graviton Hackathon is now available to developers globally to build and migrate apps to run on AWS Graviton2

This week we are celebrating 15 years of Amazon EC2 live on Twitch August 23rd – 24th with keynotes and sessions from AWS leaders and experts. You can watch all the sessions on-demand later this week to learn more about innovation at Amazon EC2.

As Jeff Barr noted in his blog, EC2 started as a single instance back in 2006 with the idea of providing developers on demand access to compute infrastructure and have them pay only for what they use. Today, EC2 has over 400 instance types with the broadest and deepest portfolio of instances in the cloud. As we strive to be the best cloud for every workload, customers consistently ask us for higher performance, and lower costs for their workloads. One way we deliver on this is by building silicon specifically optimized for the cloud. Our journey with custom silicon started in 2012 when we began looking into ways to improve the performance of EC2 instances by offloading virtualization functionality that is traditionally run on underlying servers to a dedicated offload card. Today, the AWS Nitro System is the foundation upon which our modern EC2 instances are built, delivering better performance and enhanced security. The Nitro System has also enabled us to innovate faster and deliver new instances and unique capabilities including Mac Instances, AWS Outposts, AWS Wavelength, VMware Cloud on AWS, and AWS Nitro Enclaves. We also have strong collaboration with partners to build custom silicon optimized for the AWS cloud with their latest generation processors to continue to deliver better performance and better price performance for our joint customers. Additionally, we’ve also designed AWS Inferentia and AWS Trainium chips to drive down the cost and boost performance for deep learning workloads.

One of the biggest innovations that help us deliver higher performance at lower cost for customer workloads are the AWS Graviton2 processors, which are the second generation of Arm-based processors custom-built by AWS. Instances powered by the latest generation AWS Graviton2 processors deliver up to 40% better performance at 20% lower per-instance cost over comparable x86-based instances in EC2. Additionally, Graviton2 is our most power efficient processor. In fact, Graviton2 delivers 2 to 3.5 times better performance per Watt of energy use versus any other processor in AWS.

Customers from startups to large enterprises including Intuit, Snap, Lyft, SmugMug, and Nextroll have realized significant price performance benefits for their production workloads on AWS Graviton2-based instances. Recently, EPIC Games added support for Graviton2 in Unreal Engine to help its developers build high performance games. What’s even more interesting is that AWS Graviton2-based instances supported 12 core retail services during Amazon Prime Day this year.

Most customers get started with AWS Graviton2-based instances by identifying and moving one or two workloads that are easy to migrate, and after realizing the price performance benefits, they move more workloads to Graviton2. In her blog, Liz Fong-Jones, Principal Developer Advocate at Honeycomb.io, details her journey of adopting Graviton2 and realizing significant price performance improvements. Using experience from working with thousands of customers like Liz who have adopted Graviton2, we built a program called the Graviton Challenge that provides a step-by-step plan to help you move your first workload to Graviton2-based instances.

Today, to further incentivize developers to get started with Graviton2, we are launching the Graviton Hackathon, where you can build a new app or migrate an app to run on Graviton2-based instances. Whether you are an existing EC2 user looking to optimize price performance for your workload, an Arm developer looking to leverage Arm-based instances in the cloud, or an open source developer adding support for Arm, you can participate in the Graviton Hackathon for a chance to win prizes for your project, including up to $10,000 in prize money. We look forward to the new applications which will be able to take advantage of the price performance benefits of Graviton. To learn more about Graviton2, watch the EC2 15th Birthday event sessions on-demand later this week, register to the attend the Graviton workshop at the upcoming AWS Summit Online, or register for the Graviton Challenge.

Cloud computing has made cutting edge, cost effective infrastructure available to everyday developers. Startups can use a credit card to spin up instances in minutes and scale up and scale down easily based on demand. Enterprises can leverage compute infrastructure and services to drive improved operational efficiency and customer experience. The last 15 years of EC2 innovation have been at the forefront of this shift, and we are looking forward to the next 15 years.

Confidential computing: an AWS perspective

Post Syndicated from David Brown original https://aws.amazon.com/blogs/security/confidential-computing-an-aws-perspective/

Customers around the globe—from governments and highly regulated industries to small businesses and start-ups—trust Amazon Web Services (AWS) with their most sensitive data and applications. At AWS, keeping our customers’ workloads secure and confidential, while helping them meet their privacy and data sovereignty requirements, is our highest priority. Our investments in security technologies and rigorous operational practices meet and exceed even our most demanding customers’ confidential computing and data privacy standards. Over the years, we’ve made many long-term investments in purpose-built technologies and systems to keep raising the bar of security and confidentiality for our customers.

In the past year, there has been an increasing interest in the phrase confidential computing in the industry and in our customer conversations. We’ve observed that this phrase is being applied to various technologies that solve very different problems, leading to confusion about what it actually means. With the mission of innovating on behalf of our customers, we want to offer you our perspective on confidential computing.

At AWS, we define confidential computing as the use of specialized hardware and associated firmware to protect customer code and data during processing from outside access. Confidential computing has two distinct security and privacy dimensions. The most important dimension—the one we hear most often from customers as their key concern—is the protection of customer code and data from the operator of the underlying cloud infrastructure. The second dimension is the ability for customers to divide their own workloads into more-trusted and less-trusted components, or to design a system that allows parties that do not, or cannot, fully trust one another to build systems that work in close cooperation while maintaining confidentiality of each party’s code and data.

In this post, I explain how the AWS Nitro System intrinsically meets the requirements of the first dimension by providing those protections to customers who use Nitro-based Amazon Elastic Compute Cloud (Amazon EC2) instances, without requiring any code or workload changes from the customer side. I also explain how AWS Nitro Enclaves provides a way for customers to use familiar toolsets and programming models to meet the requirements of the second dimension. Before we get to the details, let’s take a closer look at the Nitro System.

What is the Nitro System?

The Nitro System, the underlying platform for all modern Amazon EC2 instances, is a great example of how we have invented and innovated on behalf of our customers to provide additional confidentiality and privacy for their applications. For ten years, we have been reinventing the EC2 virtualization stack by moving more and more virtualization functions to dedicated hardware and firmware, and the Nitro System is a result of this continuous and sustained innovation. The Nitro System is comprised of three main parts: the Nitro Cards, the Nitro Security Chip, and the Nitro Hypervisor. The Nitro Cards are dedicated hardware components with compute capabilities that perform I/O functions, such as the Nitro Card for Amazon Virtual Private Cloud (Amazon VPC), the Nitro Card for Amazon Elastic Block Store (Amazon EBS), and the Nitro Card for Amazon EC2 instance storage.

Nitro Cards—which are designed, built, and tested by Annapurna Labs, our in-house silicon development subsidiary—enable us to move key virtualization functionality off the EC2 servers—the underlying host infrastructure—that’s running EC2 instances. We engineered the Nitro System with a hardware-based root of trust using the Nitro Security Chip, allowing us to cryptographically measure and validate the system. This provides a significantly higher level of trust than can be achieved with traditional hardware or virtualization systems. The Nitro Hypervisor is a lightweight hypervisor that manages memory and CPU allocation, and delivers performances that is indistinguishable from bare metal (we recently compared it against our bare metal instances in the Bare metal performance with the AWS Nitro System post).

The Nitro approach to confidential computing

There are three main types of protection provided by the Nitro System. The first two protections underpin the key dimension of confidential computing—customer protection from the cloud operator and from cloud system software—and the third reinforces the second dimension—division of customer workloads into more-trusted and less-trusted elements.

  1. Protection from cloud operators: At AWS, we design our systems to ensure workload confidentiality between customers, and also between customers and AWS. We’ve designed the Nitro System to have no operator access. With the Nitro System, there’s no mechanism for any system or person to log in to EC2 servers (the underlying host infrastructure), read the memory of EC2 instances, or access any data stored on instance storage and encrypted EBS volumes. If any AWS operator, including those with the highest privileges, needs to do maintenance work on the EC2 server, they can do so only by using a strictly limited set of authenticated, authorized, and audited administrative APIs. None of these APIs have the ability to access customer data on the EC2 server. Because these technological restrictions are built into the Nitro System itself, no AWS operator can bypass these controls and protections. For additional defense-in-depth against physical attacks at the memory interface level, we offer memory encryption on various EC2 instances. Today, memory encryption is enabled by default on all Graviton2-based instances (T4g, M6g, C6g, C6gn, R6g, X2g), and Intel-based M6i instances, which have Total Memory Encryption (TME). Upcoming EC2 platforms based on the AMD Milan processor will feature Secure Memory Encryption (SME).
  2. Protection from AWS system software: The unique design of the Nitro System utilizes low-level, hardware-based memory isolation to eliminate direct access to customer memory, as well as to eliminate the need for a hypervisor on bare metal instances.

    • For virtualized EC2 instances (as shown in Figure 1), the Nitro Hypervisor coordinates with the underlying hardware-virtualization systems to create virtual machines that are isolated from each other as well as from the hypervisor itself. Network, storage, GPU, and accelerator access use SR-IOV, a technology that allows instances to interact directly with hardware devices using a pass-through connection securely created by the hypervisor. Other EC2 features such as instance snapshots and hibernation are all facilitated by dedicated agents that employ end-to-end memory encryption that is inaccessible to AWS operators.

      Figure 1: Virtualized EC2 instances

      Figure 1: Virtualized EC2 instances

    • For bare metal EC2 instances (as shown in Figure 2), there’s no hypervisor running on the EC2 server, and customers get dedicated and exclusive access to all of the underlying main system board. Bare metal instances are designed for customers who want access to the physical resources for applications that take advantage of low-level hardware features—such as performance counters and Intel® VT—that aren’t always available or fully supported in virtualized environments, and also for applications intended to run directly on the hardware or licensed and supported for use in non-virtualized environments. Bare metal instances feature the same storage, networking, and other EC2 capabilities as virtualized instances because the Nitro System implements all of the system functions normally provided by the virtualization layer in an isolated and independent manner using dedicated hardware and purpose-built system firmware. We used the very same technology to create Amazon EC2 Mac instances. Because the Nitro System operates over an independent bus, we can attach Nitro cards directly to Apple’s Mac mini hardware without any other physical modifications.

      Figure 2: Bare metal EC2 instance

      Figure 2: Bare metal EC2 instance

  3. Protection of sensitive computing and data elements from customers’ own operators and software: Nitro Enclaves provides the second dimension of confidential computing. Nitro Enclaves is a hardened and highly-isolated compute environment that’s launched from, and attached to, a customer’s EC2 instance. By default, there’s no ability for any user (even a root or admin user) or software running on the customer’s EC2 instance to have interactive access to the enclave. Nitro Enclaves has cryptographic attestation capabilities that allow customers to verify that all of the software deployed to their enclave has been validated and hasn’t been tampered with. A Nitro enclave has the same level of protection from the cloud operator as a normal Nitro-based EC2 instance, but adds the capability for customers to divide their own systems into components with different levels of trust. A Nitro enclave provides a means of protecting particularly sensitive elements of customer code and data not just from AWS operators but also from the customer’s own operators and other software.As the main goal of Nitro Enclaves is to protect against the customers’ own users and software on their EC2 instances, a Nitro enclave considers the EC2 instance to reside outside of its trust boundary. Therefore, a Nitro enclave shares no memory or CPU cores with the customer instance. To significantly reduce the attack surface area, a Nitro enclave also has no IP networking and offers no persistent storage. We designed Nitro Enclaves to be a platform that is highly accessible to all developers without the need to have advanced cryptography knowledge or CPU micro-architectural expertise, so that these developers can quickly and easily build applications to process sensitive data. At the same time, we focused on creating a familiar developer experience so that developing the trusted code that runs in a Nitro enclave is as easy as writing code for any Linux environment.

Summary

To summarize, the Nitro System’s unique approach to virtualization and isolation enables our customers to secure and isolate sensitive data processing from AWS operators and software at all times. It provides the most important dimension of confidential computing as an intrinsic, on-by-default, set of protections from the system software and cloud operators, and optionally via Nitro Enclaves even from customers’ own software and operators.

What’s next?

As mentioned earlier, the Nitro System represents our almost decade-long commitment to raising the bar for security and confidentiality for compute workloads in the cloud. It has allowed us to do more for our customers than is possible with off-the-shelf technology and hardware. But we’re not stopping here, and will continue to add more confidential computing capabilities in the coming months.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

David Brown

David is the Vice President of Amazon EC2, a web service that provides secure, resizable compute capacity in the cloud. He joined AWS in 2007, as a software developer based in Cape Town, working on the early development of Amazon EC2. Over the last 12 years, he has had several roles within Amazon EC2, working on shaping the service into what it is today. Prior to joining Amazon, David worked as a software developer within a financial industry startup.

Happy 15th Birthday Amazon EC2

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/happy-15th-birthday-amazon-ec2/

Fifteen years ago today I wrote the blog post that launched the Amazon EC2 Beta. As I recall, the launch was imminent for quite some time as we worked to finalize the feature set, the pricing model, and innumerable other details. The launch date was finally chosen and it happened to fall in the middle of a long-planned family vacation to Cabo San Lucas, Mexico. Undaunted, I brought my laptop along on vacation, and had to cover it with a towel so that I could see the screen as I wrote. I am not 100% sure, but I believe that I actually clicked Publish while sitting on a lounge chair near the pool! I spent the remainder of the week offline, totally unaware of just how much excitement had been created by this launch.

Preparing for the Launch
When Andy Jassy formed the AWS group and began writing his narrative, he showed me a document that proposed the construction of something called the Amazon Execution Service and asked me if developers would find it useful, and if they would pay to use it. I read the document with great interest and responded with an enthusiastic “yes” to both of his questions. Earlier in my career I had built and run several projects hosted at various colo sites, and was all too familiar with the inflexible long-term commitments and the difficulties of scaling on demand; the proposed service would address both of these fundamental issues and make it easier for developers like me to address widely fluctuating changes in demand.

The EC2 team had to make a lot of decisions in order to build a service to meet the needs of developers, entrepreneurs, and larger organizations. While I was not part of the decision-making process, it seems to me that they had to make decisions in at least three principal areas: features, pricing, and level of detail.

Features – Let’s start by reviewing the features that EC2 launched with. There was one instance type, one region (US East (N. Virginia)), and we had not yet exposed the concept of Availability Zones. There was a small selection of prebuilt Linux kernels to choose from, and IP addresses were allocated as instances were launched. All storage was transient and had the same lifetime as the instance. There was no block storage and the root disk image (AMI) was stored in an S3 bundle. It would be easy to make the case that any or all of these features were must-haves for the launch, but none of them were, and our customers started to put EC2 to use right away. Over the years I have seen that this strategy of creating services that are minimal-yet-useful allows us to launch quickly and to iterate (and add new features) rapidly in response to customer feedback.

Pricing – While it was always obvious that we would charge for the use of EC2, we had to decide on the units that we would charge for, and ultimately settled on instance hours. This was a huge step forward when compared to the old model of buying a server outright and depreciating it over a 3 or 5 year term, or paying monthly as part of an annual commitment. Even so, our customers had use cases that could benefit from more fine-grained billing, and we launched per-second billing for EC2 and EBS back in 2017. Behind the scenes, the AWS team also had to build the infrastructure to measure, track, tabulate, and bill our customers for their usage.

Level of Detail – This might not be as obvious as the first two, but it is something that I regularly think about when I write my posts. At launch time I shared the fact that the EC2 instance (which we later called the m1.small) provided compute power equivalent to a 1.7 GHz Intel Xeon processor, but I did not share the actual model number or other details. I did share the fact that we built EC2 on Xen. Over the years, customers told us that they wanted to take advantage of specialized processor features and we began to share that information.

Some Memorable EC2 Launches
Looking back on the last 15 years, I think we got a lot of things right, and we also left a lot of room for the service to grow. While I don’t have one favorite launch, here are some of the more memorable ones:

EC2 Launch (2006) – This was the launch that started it all. One of our more notable early scaling successes took place in early 2008, when Animoto scaled their usage from less than 100 instances all the way up to 3400 in the course of a week (read Animoto – Scaling Through Viral Growth for the full story).

Amazon Elastic Block Store (2008) – This launch allowed our customers to make use of persistent block storage with EC2. If you take a look at the post, you can see some historic screen shots of the once-popular ElasticFox extension for Firefox.

Elastic Load Balancing / Auto Scaling / CloudWatch (2009) – This launch made it easier for our customers to build applications that were scalable and highly available. To quote myself, “Amazon CloudWatch monitors your Amazon EC2 capacity, Auto Scaling dynamically scales it based on demand, and Elastic Load Balancing distributes load across multiple instances in one or more Availability Zones.”

Virtual Private Cloud / VPC (2009) – This launch gave our customers the ability to create logically isolated sets of EC2 instances and to connect them to existing networks via an IPsec VPN connection. It gave our customers additional control over network addressing and routing, and opened the door to many additional networking features over the coming years.

Nitro System (2017) – This launch represented the culmination of many years of work to reimagine and rebuild our virtualization infrastructure in pursuit of higher performance and enhanced security (read more).

Graviton (2018) -This launch marked the launch of Amazon-built custom CPUs that were designed for cost-sensitive scale-out workloads. Since that launch we have continued this evolutionary line, launching general purpose, compute-optimized, memory-optimized, and burstable instances powered by Graviton2 processors.

Instance Types (2006 – Present) -We launched with one instance type and now have over four hundred, each one designed to empower our customers to address a particular use case.

Celebrate with Us
To celebrate the incredible innovation we’ve seen from our customers over the last 15 years, we’re hosting a 2-day live event on August 23rd and 24th covering a range of topics. We kick off the event with today at 9am PDT with Vice President of Amazon EC2 Dave Brown’s keynote “Lessons from 15 Years of Innovation.

Event Agenda

August 23 August 24
Lessons from 15 Years of Innovation AWS Everywhere: A Fireside Chat on Hybrid Cloud
15 Years of AWS Silicon Innovation Deep Dive on Real-World AWS Hybrid Examples
Choose the Right Instance for the Right Workload AWS Outposts: Extending AWS On-Premises for a Truly Consistent Hybrid Experience
Optimize Compute for Cost and Capacity Connect Your Network to AWS with Hybrid Connectivity Solutions
The Evolution of Amazon Virtual Private Cloud Accelerating ADAS and Autonomous Vehicle Development on AWS
Accelerating AI/ML Innovation with AWS ML Infrastructure Services Accelerate AI/ML Adoption with AWS ML Silicon
Using Machine Learning and HPC to Accelerate Product Design Digital Twins: Connecting the Physical to the Digital World

Register here and join us starting at 9 AM PT to learn more about EC2 and to celebrate along with us!

— Jeff;

How to authenticate private container registries using AWS Batch

Post Syndicated from Ben Peven original https://aws.amazon.com/blogs/compute/how-to-authenticate-private-container-registries-using-aws-batch/

This post was contributed by Clayton Thomas, Solutions Architect, AWS WW Public Sector SLG Govtech.

Many AWS Batch users choose to store and consume their AWS Batch job container images on AWS using Amazon Elastic Container Registries (ECR). AWS Batch and Amazon Elastic Container Service (ECS) natively support pulling from Amazon ECR without any extra steps required. For those users that choose to store their container images on other container registries or Docker Hub, often times they are not publicly exposed and require authentication to pull these images. Third-party repositories may throttle the number of requests, which impedes the ability to run workloads and self-managed repositories require heavy tuning to offer the scale that Amazon ECS provides. This makes Amazon ECS the preferred solution to run workloads on AWS Batch.

While Amazon ECS allows you to configure repositoryCredentials in task definitions containing private registry credentials, AWS Batch does not expose this option in AWS Batch job definitions. AWS Batch does not provide the ability to use private registries by default but you can allow that by configuring the Amazon ECS agent in a few steps.

This post shows how to configure an AWS Batch EC2 compute environment and the Amazon ECS agent to pull your private container images from private container registries. This gives you the flexibility to use your own private and public container registries with AWS Batch.

Overview

The solution uses AWS Secrets Manager to securely store your private container registry credentials, which are retrieved on startup of the AWS Batch compute environment. This ensures that your credentials are securely managed and accessed using IAM roles and are not persisted or stored in AWS Batch job definitions or EC2 user data. The Amazon ECS agent is then configured upon startup to pull these credentials from AWS Secrets Manager. Note that this solution only supports Amazon EC2 based AWS Batch compute environments, thus AWS Fargate cannot use this solution.

High-level diagram showing event flow

Figure 1: High-level diagram showing event flow

  1. AWS Batch uses an Amazon EC2 Compute Environment powered by Amazon ECS. This compute environment uses a custom EC2 Launch Template to configure the Amazon ECS agent to include credentials for pulling images from private registries.
  2. An EC2 User Data script is run upon EC2 instance startup that retrieves registry credentials from AWS Secrets Manager. The EC2 instance authenticates with AWS Secrets Manager using its configured IAM instance profile, which grants temporary IAM credentials.
  3. AWS Batch jobs can be submitted using private images that require authentication with configured credentials.

Prerequisites

For this walkthrough, you should have the following prerequisites:

  1. An AWS account
  2. An Amazon Virtual Private Cloud with private and public subnets. If you do not have a VPC, this tutorial can be followed. The AWS Batch compute environment must have connectivity to the container registry.
  3. A container registry containing a private image. This example uses Docker Hub and assumes you have created a private repository
  4. Registry credentials and/or an access token to authenticate with the container registry or Docker Hub.
  5. A VPC Security Group allowing the AWS Batch compute environment egress connectivity to the container registry.

A CloudFormation template is provided to simplify setting up this example. The CloudFormation template and provided EC2 user data script can be viewed here on GitHub.

The CloudFormation template will create the following resources:

  1. Necessary IAM roles for AWS Batch
  2. AWS Secrets Manager secret containing container registry credentials
  3. AWS Batch managed compute environment and job queue
  4. EC2 Launch Configuration with user data script

Click the Launch Stack button to get started:

Launch Stack

Launch the CloudFormation stack

After clicking the Launch stack button above, click Next to be presented with the following screen:

Figure 2: CloudFormation stack parameters

Figure 2: CloudFormation stack parameters

Fill in the required parameters as follows:

  1. Stack Name: Give your stack a unique name.
  2. Password: Your container registry password or Docker Hub access token. Note that both user name and password are masked and will not appear in any CF logs or output. Additionally, they are securely stored in an AWS Secrets Manager secret created by CloudFormation.
  3. RegistryUrl: If not using Docker Hub, specify the URL of the private container registry.
  4. User name: Your container registry user name.
  5. SecurityGroupIDs: Select your previously created security group to assign to the example Batch compute environment.
  6. SubnetIDs: To assign to the example Batch compute environment, select one or more VPC subnet IDs.

After entering these parameters, you can click through next twice and create the stack, which will take a few minutes to complete. Note that you must acknowledge that the template creates IAM resources on the review page before submitting.

Finally, you will be presented with a list of created AWS resources once the stack deployment finishes as shown in Figure 3 if you would like to dig deeper.

Figure 3: CloudFormation created resources

Figure 3: CloudFormation created resources

User data script contained within launch template

AWS Batch allows you to customize the compute environment in a variety of ways such as specifying an EC2 key pair, custom AMI, or an EC2 user data script. This is done by specifying an EC2 launch template before creating the Batch compute environment. For more information on Batch launch template support, see here.

Let’s take a closer look at how the Amazon ECS agent is configured upon compute environment startup to use your registry credentials.

MIME-Version: 1.0
Content-Type: multipart/mixed; boundary="==MYBOUNDARY=="

--==MYBOUNDARY==
Content-Type: text/cloud-config; charset="us-ascii"

packages:
- jq
- aws-cli

runcmd:
- /usr/bin/aws configure set region $(curl http://169.254.169.254/latest/meta-data/placement/region)
- export SECRET_STRING=$(/usr/bin/aws secretsmanager get-secret-value --secret-id your_secrets_manager_secret_id | jq -r '.SecretString')
- export USERNAME=$(echo $SECRET_STRING | jq -r '.username')
- export PASSWORD=$(echo $SECRET_STRING | jq -r '.password')
- export REGISTRY_URL=$(echo $SECRET_STRING | jq -r '.registry_url')
- echo $PASSWORD | docker login --username $USERNAME --password-stdin $REGISTRY_URL
- export AUTH=$(cat ~/.docker/config.json | jq -c .auths)
- echo 'ECS_ENGINE_AUTH_TYPE=dockercfg' >> /etc/ecs/ecs.config
- echo "ECS_ENGINE_AUTH_DATA=$AUTH" >> /etc/ecs/ecs.config

--==MYBOUNDARY==--

This example script uses and installs a few tools including the AWS CLI and the open-source tool jq to retrieve and parse the previously created Secrets Manager secret. These packages are installed using the cloud-config user data type, which is part of the cloud-init packages functionality. If using the provided CloudFormation template, this script will be dynamically rendered to reference the created secret, but note that you must specify the correct Secrets Manager secret id if not using the template.

After performing a Docker login, the generated Auth JSON object is captured and passed to the Amazon ECS agent configuration to be used on AWS Batch jobs that require private images. For an explanation of Amazon ECS agent configuration options including available Amazon ECS engine Auth types, see here. This example script can be extended or customized to fit your needs but must adhere to requirements for Batch launch template user data scripts, including being in MIME multi-part archive format.

It’s worth noting that the AWS CLI automatically grabs temporary IAM credentials from the associated IAM instance profile the CloudFormation stack created in order to retrieve the Secret Manager secret values. This example assumes you created the AWS Secrets Manager secret with the default AWS managed KMS key for Secrets Manager. However, if you choose to encrypt your secret with a customer managed KMS key, make sure to specify kms:Decrypt IAM permissions for the Batch compute environment IAM role.

Submitting the AWS Batch job

Now let’s try an example Batch job that uses a private container image by creating a Batch job definition and submitting a Batch job:

  1. Open the AWS Batch console
  2. Navigate to the Job Definition page
  3. Click create
  4. Provide a unique Name for the job definition
  5. Select the EC2 platform
  6. Specify your private container image located in the Image field
  7. Click create

Figure 4: Batch job definition

Now you can submit an AWS Batch job that uses this job definition:

  1. Click on the Jobs page
  2. Click Submit New Job
  3. Provide a Name for the job
  4. Select the previously created job definition
  5. Select the Batch Job Queue created by the CloudFormation stack
  6. Click Submit
Submitting a new Batch job

Figure 5: Submitting a new Batch job

After submitting the AWS Batch job, it will take a few minutes for the AWS Batch Compute Environment to create resources for scheduling the job. Once that is done, you should see a SUCCEEDED status by viewing the job and filtering by AWS Batch job queue shown in Figure 6.

Figure 6: AWS Batch job succeeded

Figure 6: AWS Batch job succeeded

Cleaning up

To clean up the example resources, click delete for the created CloudFormation stack in the CloudFormation Console.

Conclusion

In this blog, you deployed a customized AWS Batch managed compute environment that was configured to allow pulling private container images in a secure manner. As I’ve shown, AWS Batch gives you the flexibility to use both private and public container registries. I encourage you to continue to explore the many options available natively on AWS for hosting and pulling container images. Amazon ECR or the recently launched Amazon ECR public repositories (for a deeper dive, see this blog announcement) both provide a seamless experience for container workloads running on AWS.

Create CIS hardened Windows images using EC2 Image Builder

Post Syndicated from Vinay Kuchibhotla original https://aws.amazon.com/blogs/devops/cis-windows-ec2-image-builder/

Many organizations today require their systems to be compliant with the CIS (Center for Internet Security) Benchmarks. Enterprises have adopted the guidelines or benchmarks drawn by CIS to maintain secure systems. Creating secure Linux or Windows Server images on the cloud and on-premises can involve manual update processes or require teams to build automation scripts to maintain images. This blog post details the process of automating the creation of CIS compliant Windows images using EC2 Image Builder.

EC2 Image Builder simplifies the building, testing, and deployment of Virtual Machine and container images for use on AWS or on-premises. Keeping Virtual Machine and container images up-to-date can be time consuming, resource intensive, and error-prone. Currently, customers either manually update and snapshot VMs or have teams that build automation scripts to maintain images. EC2 Image Builder significantly reduces the effort of keeping images up-to-date and secure by providing a simple graphical interface, built-in automation, and AWS-provided security settings. With Image Builder, there are no manual steps for updating an image nor do you have to build your own automation pipeline. EC2 Image Builder is offered at no cost, other than the cost of the underlying AWS resources used to create, store, and share the images.

Hardening is the process of applying security policies to a system and thereby, an Amazon Machine Image (AMI) with the CIS security policies in place would be a CIS hardened AMI. CIS benchmarks are a published set of recommendations that describe the security policies required to be CIS-compliant. They cover a wide range of platforms including Windows Server and Linux. For example, a few recommendations in a Windows Server environment are to:

  • Have a password requirement and rotation policy.
  • Set an idle timer to lock the instance if there is no activity.
  • Prevent guest users from using Remote Desktop Protocol (RDP) to access the instance.

While Deploying CIS L1 hardened AMIs with EC2 Image Builder discusses about Linux AMIs, this blog post demonstrates how EC2 Image Builder can be used to publish hardened Windows 2019 AMIs. This solutions uses the following AWS services:

EC2 Image Builder provides all the necessary resources needed for publishing AMIs and that involves –

  • Creating a pipeline by providing details such as a name, description, tags, and a schedule to run automated builds.
  • Creating a recipe by providing a name and version, select a source operating system image, and choose components to add for building and testing. Components are the building blocks that are consumed by an image recipe or a container recipe. For example, packages for installation, security hardening steps, and tests. The selected source operating system image and components make up an image recipe.
  • Defining infrastructure configuration – Image Builder launches Amazon EC2 instances in your account to customize images and run validation tests. The Infrastructure configuration settings specify infrastructure details for the instances that will run in your AWS account during the build process.
  • After the build is complete and has passed all its tests, the pipeline automatically distributes the developed AMIs to the select AWS accounts and regions as defined in the distribution configuration.
    More details on creating an Image Builder pipeline using the AWS console wizard can be found here.

Solution Overview and prerequisites

The objective of this pipeline is to publish CIS L1 compliant Windows 2019 AMIs and this is achieved by applying a Windows Group Policy Object(GPO) stored in an Amazon S3 bucket for creating the hardened AMIs. The workflow includes the following steps:

  • Download and modify the CIS Microsoft Windows Server 2019 Benchmark Build Kit available on the Center for Internet Security website. Note: Access to the benchmarks on the CIS site requires a paid subscription.
  • Upload the modified GPO file to an S3 bucket in an AWS account.
  • Create a custom Image Builder component by referencing the GPO file uploaded to the S3 bucket.
  • Create an IAM Instance Profile that the
  • Launch the EC2 Image Builder pipeline for publishing CIS L1 hardened Windows 2019 AMIs.

Make sure to have these prerequisites checked before getting started:

Implementation

Now that you have the prerequisites met, let’s begin with modifying the downloaded GPO file.

Creating the GPO File

This step involves modifying two files, registry.pol and GptTmpl.inf

  • On your workstation, create a folder of your choice, lets say C:\Utils
  • Move both the CIS Benchmark build kit and the LGPO utility to C:\Utils
  • Unzip the benchmark file to C:\Utils\Server2019v1.1.0. You should find the following folder structure in the benchmark build kit.

Screenshot of folder structure

  • To make the GPO file work with AWS EC2 instances, you need to change the GPO file to prevent it from applying the following CIS recommendations mentioned in the below table and execute the commands mentioned below the table for getting there:


Benchmark rule # Recommendation Value to be configured Reason
2.2.21 (L1) Configure ‘Deny Access to this computer from the network’ Guests Does not include ‘Local account and member of Administrators group’ to allow for remote login.
2.2.26 (L1) Ensure ‘Deny log on through Remote Desktop Services’ is set to include ‘Guests, Local account’ Guests Does not include ‘Local account’ to allow for RDP login.
2.3.1.1 (L1) Ensure ‘Accounts: Administrator account status’ is set to ‘Disabled’ Not Configured Administrator account remains enabled in support of allowing login to the instance after launch.
2.3.1.5 (L1) Ensure ‘Accounts: Rename administrator account’ is configured Not Configured We have retained “Administrator” as the default administrative account for the sake of provisioning scripts that may not have knowledge of “CISAdmin” as defined in the CIS remediation kit.
2.3.1.6 (L1) Configure ‘Accounts: Rename guest account’ Not Configured Sysprep process renames this account to default of ‘Guest’.
2.3.7.4 Interactive logon: Message text for users attempting to log on Not Configured This recommendation is not configured as it causes issues with AWS Scanner.
2.3.7.5 Interactive logon: Message title for users attempting to log on Not Configured This recommendation is not configured as it causes issues with AWS Scanner.
9.3.5 (L1) Ensure ‘Windows Firewall: Public: Settings: Apply local firewall rules’ is set to ‘No’ Not Configured This recommendation is not configured as it causes issues with RDP.
9.3.6 (L1) Ensure ‘Windows Firewall: Public: Settings: Apply local connection security rules’ Not Configured This recommendation is not configured as it causes issues with RDP.
18.2.1 (L1) Ensure LAPS AdmPwd GPO Extension / CSE is installed (MS only) Not Configured LAPS is not configured by default in the AWS environment.
18.9.58.3.9.1 (L1) Ensure ‘Always prompt for password upon connection’ is set to ‘Enabled’ Not Configured This recommendation is not configured as it causes issues with RDP.


  • Parse the policy file located inside MS-L1\{6B8FB17A-45D6-456D-9099-EB04F0100DE2}\DomainSysvol\GPO\Machine\registry.pol into a text file using the command:

C:\Utils\LGPO.exe /parse /m C:\Utils\Server2019v1.1.0\MS-L1\DomainSysvol\GPO\Machine\registry.pol >> C:\Utils\MS-L1.txt

  • Open the generated MS-L1.txt file and delete the following sections:

Computer
Software\Policies\Microsoft\Windows NT\Terminal Services
fPromptForPassword
DWORD:1

Computer
Software\Policies\Microsoft\WindowsFirewall\PublicProfile
AllowLocalPolicyMerge
DWORD:0

Computer
Software\Policies\Microsoft\WindowsFirewall\PublicProfile
AllowLocalIPsecPolicyMerge
DWORD:0

  • Save the file and convert it back to policy file using command:

C:\Utils\LGPO.exe /r C:\Utils\MS-L1.txt /w C:\Utils\registry.pol

  • Copy the newly generated registry.pol file from C:\Utils\ to C:\Utils\Server2019v1.1.0\MS-L1\DomainSysvol\GPO\Machine\. Note:This will replace the existing registry.pol file.
  • Next, open C:\Utils\Server2019v1.1.0\MS-L1\DomainSysvol\GPO\Machine\microsoft\windows nt\SecEdit\GptTmpl.inf using Notepad.
  • Under the [System Access] section, delete the following lines:

NewAdministratorName = "CISADMIN"
NewGuestName = "CISGUEST"
EnableAdminAccount = 0

  • Under the section [Privilege Rights], modify the values as given below:

SeDenyNetworkLogonRight = *S-1-5-32-546
SeDenyRemoteInteractiveLogonRight = *S-1-5-32-546

  • Under the section [Registry Values], remove the following two lines:

MACHINE\Software\Microsoft\Windows\CurrentVersion\Policies\System\LegalNoticeCaption=1,"ADD TEXT HERE"
MACHINE\Software\Microsoft\Windows\CurrentVersion\Policies\System\LegalNoticeText=7,ADD TEXT HERE

  • Save the C:\Utils\Server2019v1.1.0\MS-L1\DomainSysvol\GPO\Machine\microsoft\windows nt\SecEdit\GptTmpl.inf file.
  • Rename the root folder C:\Utils\Server2019v1.1.0 to a simpler name like C:\Utilis\gpos
  • Compress both the C:\Utilis\gpos folder along with the C:\Utils\LGPO.exe file and name it as C:\Utilis\cisbuild.zip and upload it to the image-builder-assets S3 bucket.

Create Build Component

Next step for us is to develop the build component file that details what gets to be installed on the AMI that will be created at the end of the process. For example, you can use the component definition for installing external tools like Python. To build a component, you must provide a YAML-based document, which represents the phases and steps to create the component. Create the CISL1Component following the below steps:

  • Login to the AWS Console and open the EC2 Image Builder dashboard.
  • Click on Components in the left pane.
  • Click on Create Component.
  • Choose Windows for Image Operating System (OS).
  • Type a name for the Component, in this case, we will name it as CIS-Windows-2019-Build-Component.
  • Type in a component version. Since it is the first version, we will choose 1.0.0
  • Optionally, under KMS keys, if you have a custom KMS key to encrypt the image, you can choose that or leave as default.
  • Type in a meaningful description.
  • Under Definition Document, choose “Define document content” and paste the following YAML code:

name: CISLevel1Build
description: Build Component to build a CIS Level 1 Image along with additional libraries
schemaVersion: 1.0

phases:
  - name: build
    steps:
      - name: DownloadUtilities
        action: ExecutePowerShell
        inputs:
          commands:
            - New-Item -ItemType directory -Path C:\Utils
            - Invoke-WebRequest -Uri "https://www.python.org/ftp/python/3.8.2/python-3.8.2-amd64.exe" -OutFile "C:\Utils\python.exe"
      - name: BuildKitDownload
        action: S3Download
        inputs:
          - source: s3://image-builder-assets/cisbuild.zip
            destination: C:\Utils\BuildKit.zip
      - name: InstallPython
        action: ExecuteBinary
        onFailure: Continue
        inputs:
          path: 'C:\Utils\python.exe'
          arguments:
            - '/quiet'
      - name: InstallGPO
        action: ExecutePowerShell
        inputs:
          commands:
            - Expand-Archive -LiteralPath C:\Utils\BuildKit.Zip -DestinationPath C:\Utils
            - "$GPOPath=Get-ChildItem -Path C:\\Utils\\gpos\\USER-L1 -Exclude \"*.xml\""
            - "&\"C:\\Utils\\LGPO.exe\" /g \"$GPOPath\""
            - "$GPOPath=Get-ChildItem -Path C:\\Utils\\gpos\\MS-L1 -Exclude \"*.xml\""
            - "&\"C:\\Utils\\LGPO.exe\" /g \"$GPOPath\""
            - New-NetFirewallRule -DisplayName "WinRM Inbound for AWS Scanner" -Direction Inbound -Action Allow -EdgeTraversalPolicy Block -Protocol TCP -LocalPort 5985
      - name: RebootStep
        action: Reboot
        onFailure: Abort
        maxAttempts: 2
        inputs:
          delaySeconds: 60


The above template has a build phase with the following steps:

  • DownloadUtilities – Executes a command to create a directory (C:\Utils) and another command to download Python from the internet and save it in the created directory as python.exe. Both are executed in PowerShell.
  • BuildKitDownload – Downloads the GPO archive created in the previous section from the bucket we stored it in.
  • InstallPython – Installs Python in the system using the executable downloaded in the first step.
  • InstallGPO – Installs the GPO files we prepared from the previous section to apply the CIS security policies. In this example, we are creating a Level 1 CIS hardened AMI.
    • Note: In order to create a Level 2 CIS hardened AMIs, you need to apply User-L1, User-L2, MS-L1, MS-L2 GPOs.
    • To apply the policy, we use the LGPO.exe tool and run the following command:
      LGPO.exe /g "Path\of\GPO\directory"
    • As an example, to apply the MS-L1 GPO, the command would be as follows:
      LGPO.exe /g "C:\Utils\gpos\MS-L1\DomainSysvol"
    • The last command opens the 5985 port in the firewall to allow AWS Scanner inbound connection. This is a CIS recommendation.
  • RebootStep – Reboots the instance after applying the security policies. A reboot is necessary to apply the policies.

Note: If you need to run any tests/validation you need to include another phase to run the test scripts. Guidelines on that can be found here.

Create an instance profile role for the Image Pipeline

Image Builder launches Amazon EC2 instances in your account to customize images and run validation tests. The Infrastructure configuration settings specify infrastructure details for the instances that will run in your AWS account during the build process. In this step, you will create an IAM Role to attach to the instance that the Image Pipeline will use to create an image. Create the IAM Instance Profile following the below steps:

  • Open the AWS Identity and Access Management (AWS IAM) console and click on Roles on the left pane.
  • Click on Create Role.
  • Choose AWS service for trusted entity and choose EC2 and click Next.
  • Attach the following policies: AmazonEC2RoleforSSM, AmazonS3ReadOnlyAccess, EC2InstanceProfileForImageBuilder and click Next.
  • Optionally, add tags and click Next
  • Give the role a name and description and review if all the required policies are attached. In this case, we will name the IAM Instance Profile as CIS-Windows-2019-Instance-Profile
  • Click Create role.

Create Image Builder Pipeline

In this step, you create the image pipeline which will produce the desired AMI as an output. Image Builder image pipelines provide an automation framework for creating and maintaining custom AMIs and container images. Pipelines deliver the following functionality:

  • Assemble the source image, components for building and testing, infrastructure configuration, and distribution settings.
  • Facilitate scheduling for automated maintenance processes using the Schedule builder in the console wizard, or entering cron expressions for recurring updates to your images.
  • Enable change detection for the source image and components, to automatically skip scheduled builds when there are no changes.

To create an Image Builder pipeline, perform the following steps:

  • Open the EC2 Image Builder console and choose create Image Pipeline.
  • Select Windows for the Image Operating System.
  • Under Select Image, choose Select Managed Images and browse for the latest Windows Server 2019 English Full Base x86 image.
  • Under Build components, choose the Build component CIS-Windows-2019-Build-Component created in the previous section.
  • Optionally, under Tests, if you have a test component created, you can select that.
  • Click Next.
  • Under Pipeline details, give the pipeline a name and a description. For IAM role, select the role CIS-Windows-2019-Instance-Profile that was created in the previous section.
  • Under Build Schedule, you can choose how frequently you want to create an image through this pipeline based on an update schedule. You can select Manual for now.
  • (Optional) Under Infrastructure Settings, select an instance type to customize your image for that type, an Amazon SNS topic to get alerts from as well as Amazon VPC settings. If you would like to troubleshoot in case the pipeline faces any errors, you can uncheck “Terminate Instance on failure” and choose an EC2 Key Pair to access the instance via Remote Desktop Protocol (RDP). You may wish to store the Logs in an S3 bucket as well. Note: Make sure the chosen VPC has outbound access to the internet in case you are downloading anything from the web as part of the custom component definition.
  • Click Next.
  • Under Configure additional settings, you can optionally choose to attach any licenses that you own through AWS License Manager to the AMI.
  • Under Output AMI, give a name and optional tags.
  • Under AMI distribution settings, choose the regions or AWS accounts you want to distribute the image to. By default, your current region is included. Click on Review.
  • Review the details and click Create Pipeline.
  • Since we have chosen Manual under the Build Schedule, manually trigger the Image Builder pipeline for kicking off the AMI creation process. On successful run, Image Builder pipeline will create the image and the output image can be found under Images on the left pane of the EC2 Image Builder console.
  • To troubleshoot any issues, the reasons for failure can be found by clicking on the Image Pipeline you created and view the corresponding output image with the Status as Failed.

Cleanup

Following the above detailed step-by-step process creates EC2 Image Builder Pipeline, Custom Component and an IAM Instance Profile. While none of these resources have any costs associated with them, you are charged for the runtime of the EC2 instance used during the AMI built process and the EBS volume costs associated with the size of the AMI. Make sure to clear the AMIs when not needed for avoiding any unwanted costs.

Conclusion

This blog post demonstrated how you can use EC2 Image Builder to create a CIS L1 hardened Windows 2019 Image in an automated fashion. Additionally, this post also demonstrated on how you can use build components to install any dependencies or executables from different sources like the internet or from an Amazon S3 bucket. Feel free to test this solution in your AWS accounts and provide feedback.

New – Amazon EC2 M6i Instances Powered by the Latest-Generation Intel Xeon Scalable Processors

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-amazon-ec2-m6i-instances-powered-by-the-latest-generation-intel-xeon-scalable-processors/

Last year, we introduced the sixth generation of EC2 instances powered by AWS-designed Graviton2 processors. We’re now expanding our sixth-generation offerings to include x86-based instances, delivering price/performance benefits for workloads that rely on x86 instructions.

Today, I am happy to announce the availability of the new general purpose Amazon EC2 M6i instances, which offer up to 15% improvement in price/performance versus comparable fifth-generation instances. The new instances are powered by the latest generation Intel Xeon Scalable processors (code-named Ice Lake) with an all-core turbo frequency of 3.5 GHz.

You might have noticed that we’re now using the “i” suffix in the instance type to specify that the instances are using an Intel processor. We already use the suffix “a” for AMD processors (for example, M5a instances) and “g” for Graviton processors (for example, M6g instances).

Compared to M5 instances using an Intel processor, this new instance type provides:

  • A larger instance size (m6i.32xlarge) with 128 vCPUs and 512 GiB of memory that makes it easier and more cost-efficient to consolidate workloads and scale up applications.
  • Up to 15% improvement in compute price/performance.
  • Up to 20% higher memory bandwidth.
  • Up to 40 Gbps for Amazon Elastic Block Store (EBS) and 50 Gbps for networking.
  • Always-on memory encryption.

M6i instances are a good fit for running general-purpose workloads such as web and application servers, containerized applications, microservices, and small data stores. The higher memory bandwidth is especially useful for enterprise applications, such as SAP HANA, and high performance computing (HPC) workloads, such as computational fluid dynamics (CFD).

M6i instances are also SAP-certified. For over eight years SAP customers have been relying on the Amazon EC2 M-family of instances for their mission critical SAP workloads. With M6i instances, customers can achieve up to 15% better price/performance for SAP applications than M5 instances.

M6i instances are available in nine sizes (the m6i.metal size is coming soon):

Name vCPUs Memory
(GiB)
Network Bandwidth
(Gbps)
EBS Throughput
(Gbps)
m6i.large 2 8 Up to 12.5 Up to 10
m6i.xlarge 4 16 Up to 12.5 Up to 10
m6i.2xlarge 8 32 Up to 12.5 Up to 10
m6i.4xlarge 16 64 Up to 12.5 Up to 10
m6i.8xlarge 32 128 12.5 10
m6i.12xlarge 48 192 18.75 15
m6i.16xlarge 64 256 25 20
m6i.24xlarge 96 384 37.5 30
m6i.32xlarge 128 512 50 40

The new instances are built on the AWS Nitro System, which is a collection of building blocks that offloads many of the traditional virtualization functions to dedicated hardware, delivering high performance, high availability, and highly secure cloud instances.

For optimal networking performance on these new instances, upgrade your Elastic Network Adapter (ENA) drivers to version 3. For more information, see this article about how to get maximum network performance on sixth-generation EC2 instances.

M6i instances support Elastic Fabric Adapter (EFA) on the m6i.32xlarge size for workloads that benefit from lower network latency, such as HPC and video processing.

Availability and Pricing
EC2 M6i instances are available today in six AWS Regions: US East (N. Virginia), US West (Oregon), US East (Ohio), Europe (Ireland), Europe (Frankfurt), and Asia Pacific (Singapore). As usual with EC2, you pay for what you use. For more information, see the EC2 pricing page.

— Danilo

Field Notes: Implementing HA and DR for Microsoft SQL Server using Always On Failover Cluster Instance and SIOS DataKeeper

Post Syndicated from Sudhir Amin original https://aws.amazon.com/blogs/architecture/field-notes-implementing-ha-and-dr-for-microsoft-sql-server-using-always-on-failover-cluster-instance-and-sios-datakeeper/

To ensure high availability (HA) of Microsoft SQL Server in Amazon Elastic Compute Cloud (Amazon EC2), there are two options: Always On Failover Cluster Instance (FCI) and Always On availability groups. With a wide range of networking solutions such as VPN and AWS Direct Connect, you have options to further extend your HA architecture to another AWS Region to also meet your disaster recovery (DR) objectives.

You can also run asynchronous replication between Regions, or a combination of both synchronous replication between Availability Zones and asynchronous replication between Regions.

Choosing the right SQL Server HA solution depends on your requirements. If you have hundreds of databases, or are looking to avoid the expense of SQL Server Enterprise Edition, then SQL Server FCI is the preferred option. If you are looking to protect user-defined databases and system databases that hold agent jobs, usernames, passwords, and so forth, then SQL Server FCI is the preferred option. If you already own SQL Server Enterprise licenses we recommend continuing with that option.

On-premises Always On FCI deployments typically require shared storage solutions such as a fiber channel storage area network (SAN). When deploying SQL Server FCI in AWS, a SAN is not a viable option. Although Amazon FSx for Microsoft Windows is the recommended storage option for SQL Server FCI in AWS, it does not support adding cluster nodes in different Regions. To build a SQL Server FCI that spans both Availability Zones and Regions, you can use a solution such as SIOS DataKeeper.

In this blog post, we will show you how SIOS DataKeeper solves both HA and DR requirements for customers by enabling a SQL Server FCI that spans both Availability Zones and Regions. Synchronous replication will be used between Availability Zones for HA, while asynchronous replication will be used between Regions for DR.

Architecture overview

We will create a three-node Windows Server Failover Cluster (WSFC) with the configuration shown in Figure 1 between two Regions. Virtual private cloud (VPC) peering was used to enable routing between the different VPCs in each Region.

High-level architecture showing two cluster nodes replicating synchronously between Availability Zones.

Figure 1 – High-level architecture showing two cluster nodes replicating synchronously between Availability Zones.

Walkthrough

SIOS DataKeeper is a host-based, block-level volume replication solution that integrates with WSFC to enable what is known as a SANLess cluster. DataKeeper runs on each cluster node and has two primary functions: data replication and cluster integration through the DataKeeper volume cluster resource.

The DataKeeper volume resource takes the place of the traditional Cluster Disk resource found in a SAN-based cluster. Upon failover, the DataKeeper volume resource controls the replication direction, ensuring the active cluster node becomes the source of the replication while all the remaining nodes become the target of the replication.

After the SANLess cluster is configured, it is managed through Windows Server Failover Cluster Manager just like its SAN-based counterpart. Configuration of DataKeeper can be done through the DataKeeper UI, CLI, or PowerShell. AWS CloudFormation templates can also be used for automated deployment, as shown in AWS Quick Start.

The following steps explain how to configure a three-node SQL Server SANless cluster with SIOS DataKeeper.

Prerequisites

  • IAM permissions to create VPCs and VPC Peering connection between them.
  • A VPC that spans two Availability Zones and includes two private subnets to host Primary and Secondary SQL Server.
  • Another VPC with single Availability Zone and includes one private subnet to host Tertiary SQL Server Node for Disaster Recovery.
  • Subscribe to the SIOS DataKeeper Cluster Edition AMI in the AWS Marketplace, or sign up for FTP download for SIOS Cluster Edition software.
  • An existing deployment of Active Directory with networking access to support the Windows Failover Cluster and SQL Deployment. Active Directory can deployed on EC2 with AWS Launch Wizard for Active Directory or through our Quick Start for Active Directory.
  • Active Directory Domain administrator account credentials.

Configuring a three-node cluster

Step 1: Configure the EC2 instances

It’s good practice to record the system and network configuration details as shown below[SM1]. Indicate the hostname, volume information, and networking configuration of each cluster node. Each node requires a primary IP address and two secondary IP addresses, one for the core cluster resource and one for the SQL Server client listener.

The example shown in Figure 2 uses a single volume; however, it is completely acceptable to use multiple volumes in your SQL Server FCI.

Figure 2 – Shows Storage, Network and AWS Configuration details of all threes cluster nodes

Figure 2 – Shows Storage, Network and AWS Configuration details of all threes cluster nodes

Due to Region and Availability Zone constructs, each cluster node will reside in a different subnet. A cluster that spans multiple subnets is referred to as a multi-subnet failover cluster. Refer to Create a failover cluster and SQL Server Multi-Subnet Clustering to learn more.

Step 2: Join the domain

With properly configured networking and security groups, DNS name resolution, and Active Directory credentials with required permissions, join all the cluster nodes to the domain. You can use AWS Managed Microsoft AD or manage your own Microsoft Active Directory domain controllers.

Step 3: Create the basic cluster

  1. Install the Failover Clustering feature and its prerequisite software components on all three nodes using PowerShell, shown in the following example.
    Install-WindowsFeature -Name Failover-Clustering -IncludeManagementTools
  2. Run cluster validation [CA2] [CA3] using PowerShell, shown in the following example.
    Test-Cluster -Node wsfcnode1.awslab.com, wsfcnode2.awslab.com, drnode.awslab.com
    NOTE: Windows PowerShell cmdlet Test-Cluster tests the underlying hardware and software, directly and individually, to obtain an accurate assessment of how well Failover Clustering can be supported in a given configuration with the following steps.
  3. Create the cluster using PowerShell, shown in the following example.
    New-Cluster -Name WSFCCluster1 -NoStorage -StaticAddress 10.0.0.101, 10.0.32.101, 11.0.0.101 -Node wsfcnode1.awslab.com, wsfcnode2.awslab.com, drnode.awslab.com
  4. For more information using PowerShell for WSFC, view Microsoft’s documentation.
  5. It is always best practice to configure a file share witness and add it to your cluster quorum. You can use Amazon FSx for Windows to provide a Server Message Block (SMB) share, or you can create a file share on another domain joined server in your environment. See the following for more documentation for more details.

A successful implementation will show all three nodes UP (shown in Figure 3) in the Failover Cluster Manager.

Figure 3 –Shows all three nodes status participating in Windows Failover Cluster

Figure 3 – Shows all three nodes status participating in Windows Failover Cluster

Step 4: Configure SIOS DataKeeper

After the basic cluster is created, you are ready to proceed with the DataKeeper configuration. Below are the basic steps to configure DataKeeper. For more detailed instructions, review the SIOS documentation.

Step 4.1: Install DataKeeper on all three nodes

  • After you sign up for a free demo, SIOS provides you with an FTP URL to download the software package of SIOS Datakeeper Cluster edition. Use the FTP URL to download and run the latest software release.
  • Choose Next, and read and accept the license terms.
  • By Default, both components SIOS Datakeeper Server Components and SIOS DataKeeper User Interface will be selected. Choose Next to proceed.
  • Accept the default install location, and choose Next.
  • Next, you will be prompted to accept the system configuration changes to add firewall exceptions for the required ports. Choose Yes to enable.
  • Enter credentials for SIOS Service account, and choose Next.
  • Finally, choose Yes, and then Finish, to restart your system.

Step 4.2: Relocate the intent log (bitmap) file to the ephemeral drive

  • Relocate the bitmap file to the ephemeral drive (confirm the ephemeral drive uses Z:\ for its drive letter).
  • SIOS DataKeeper uses an intent log (also referred to as a bitmap file) to track changes made to the source, or to target volume during times that the target is unlocked. SIOS recommends to use ephemeral storage as a preferred location for the intent log to minimize the performance impact associated with the intent log. By default, SIOS InstallShield Wizard will store the bitmap at: “C:\Program Files (x86) \SIOS\DataKeeper\Bitmaps”.
  • To change the intent log location, make the following registry changes. Edit registry through regedit. “HKEY_LOCAL_MACHINE\SYSTEM\CurrentControlSet\Services\ExtMirr\Parameter”
  • Modify the “BitmapBaseDir” parameter by changing to the new location (i.e.s, Z:\), and then reboot your system.
  • To ensure the ephemeral drive is reattached upon reboot, specify volume settings in the DriveLetterMappingConfig.json, and save the file under the location.
    “C:\ProgramData\Amazon\EC2-Windows\Launch\Config\DriveLetterMappingConfig.json”.

    { 
      "driveLetterMapping": [
      {
       "volumeName": "Temporary Storage 0",
       "driveLetter": "Z"
      },
      {
       "volumeName": "Data",
        "driveLetter": "D"
      }
     ]
    }
    
  • Next, open Windows PowerShell and use the following command to run the EC2Launch script that initializes the disks:
    C:\ProgramData\Amazon\EC2-Windows\Launch\Scripts\InitializeDisks.ps1 -ScheduleFor more information, see EC2Launch documentation.NOTE: If you are using the SIOS DataKeeper Marketplace AMI, you can skip the previous steps to install SIOS Software and relocating bitmap file, and continue with the following steps.

Step 4.3: Create a DataKeeper job

  • Open SIOS DataKeeper application. From the right-side Actions panel, select Create Job.
  • Enter Job name and Job description, and then choose Create Job.
  • A create mirror wizard will open. In this job, we will set up a mirror relationship between WSFCNode1(Primary) and WSFCNode2(Secondary) within us-east-1 using synchronous replication.
    Select the source WSFCNode1.awscloud.com and volume D. Choose Next to proceed.

    NOTE: The volume on both the source and target systems must be NTFS file system type, and the target volume must be greater than or equal to the size of the source volume.
  • Choose the target WSFCNODE2.awscloud.com and correctly-assigned volume drive D.
  • Now, select how the source volume data should be sent to the target volume.
    For our design, choose Synchronous replication for nodes within us-east-1.
  • After you choose Done, you will be prompted to register the volume into Windows Failover Cluster as a clustered datakeeper volume as a storage resource. When prompted, choose Yes.
  • After you have successfully created the first mirror you will see the status of the mirror job (as shown in Figure 4).
    If you have additional volumes, repeat the previous steps for each additional volume.

    Figure 4 – Shows the SIOS Datakeeper Job Summary of mirrored volume between WFSCNODE1 & WSFCNODE2

    Figure 4 – Shows the SIOS Datakeeper Job Summary of mirrored volume between WFSCNODE1 & WSFCNODE2

  • If you have additional volumes, repeat the previous steps for each additional volume.

Step 4.4: Add another mirror pair to the same job using asynchronous replication between nodes residing in different AWS Regions (us-east-1 and us-east-2)

  • Open the create mirror wizard from the right-side action pane.
  • Choose the source WSFCNode1.awscloud.com and volume D.
  • For Server, enter DRNODE.awscloud.com.
  • After you are connected, select the target DRNODE.awscloud.com and assigned volume D.
  • For, How should the source volume data be sent to the target volume?, choose Asynchronous replication for nodes between us-east-1 and us-east-2.
  • Choose Done to finish, and a pop-up window will provide you with additional information on action to take in the event of failover.
  • You configured WSFCNode1.awscloud.com to mirror asynchronously to DRNODE.awscloud.com. However, during the event of failover, WSFCNode2.awscloud.com will become the new owner of the Failover Cluster and therefore own the source volume. This function of SIOS DataKeeper, called switchover, automatically changes the source of the mirror to the new owner of the Windows Failover Cluster. For our example, SIOS DataKeeper will automatically perform a switchover function to create a new mirror pair between WSFCNODE2.awscloud.com and DRNODE.awscloud.com. Therefore, select Asynchronous mirror type, and choose OK. For more information, see Switchover and Failover with Multiple Targets.
  • A successfully-configured job will appear under Job Overview.


If you prefer to script the process of creating the DataKeeper job, and adding the additional mirrors, you can use the DataKeeper CLI as described in How to Create a DataKeeper Replicated Volume that has Multiple Targets via CLI.

If you have done everything correctly, the DataKeeper UI will look similar to the following image.

Furthermore, Failover Cluster Manager will show the Datakeeper Volume D, online, registered.

Step 5: Install the SQL Server FCI

  • Install SQL Server on WSFCNode1 with the New SQL Server failover cluster installation option in the SQL Server installer.
  • Install SQL Server on WSFCNode2 with the Add node to a SQL Server failover cluster option in the SQL Server installer.
  • If you are using SQL Server Enterprise Edition, install SQL Server on DRNode using the “Add Node to Existing Cluster” option in the SQL Server installer.
  • If you are using SQL Server Standard Edition, you will not be able to add the DR node to the cluster. Follow the SIOS documentation: Accessing Data on the Non-Clustered Disaster Recovery Node.

For detailed information on installing a SQL Server FCI, visit SQL Server Failover Cluster Installation.

At the end of installation, your Failover Cluster Manager will look similar to the following image.

Step 6: Client redirection considerations

When you install SQL Server into a multi-subnet cluster, RegisterAllProvidersIP is set to true. With that setting enabled, your DNS Server will register three Name Records (A), each using the name that you used when you created the SQL Listener during the SQL Server FCI installation. Each Name (A) record will have a different IP address, one for each of the cluster IP addresses that are associated with that cluster name resource.

If your clients are using .NET Framework 4.6.1 or later, the clients will manage the cross-subnet failover automatically. If your clients are using .NET Framework 4.5 through 4.6, then you will need to add MultiSubnetFailover=true to your connection string.

If you have an older client that does not allow you to add the MultiSubnetFailover=true parameter, then you will need to change the way that the failover cluster behaves. First, set the RegisterAllProvidersIP to false, so that only one Name (A) record will be entered in DNS. Each time the cluster fails over the name resource, the Name (A) record in DNS will be updated with the cluster IP address associated with the node coming online. Finally, adjust the TTL of the Name (A) record so that the clients do not have to wait the default 20 minutes before the TTL expires and the IP address is refreshed.

In the following PowerShell, you can see how to change the RegisterAllProvidersIP setting and update the TTL to 30 seconds.

Get-ClusterResource "sql name resource" | Set-ClusterParameter RegisterAllProvidersIP 0  
Set-ClusterParameter -Name HostRecordTTL 30

Cleanup

When you are finished, you can terminate all three EC2 instances you launched.

Conclusion

Deploying a SQL Server FCI, that includes both Availability Zones and AWS Regions, is ideal for a solution that includes HA and DR. Although AWS provides the necessary infrastructure in terms of compute and networking, it is the combination of SIOS DataKeeper with WSFC that makes this configuration possible.

The solution described in this blogpost works with all supported versions of Windows Failover Cluster and SQL Server. Other configurations, such as hybrid-cloud and multi-cloud, are also possible. If adequate networking is in place, and Windows Server is running, where the cluster nodes reside is entirely up to you.

Field Notes provides hands-on technical guidance from AWS Solutions Architects, consultants, and technical account managers, based on their experiences in the field solving real-world business problems for customers.

Insights for CTOs: Part 1 – Building and Operating Cloud Applications

Post Syndicated from Syed Jaffry original https://aws.amazon.com/blogs/architecture/insights-for-ctos-part-1-building-and-operating-cloud-applications/

This 6-part series shares insights gained from various CTOs during their cloud adoption journeys at their respective organizations. This post takes those learnings and summarizes architecture best practices to help you build and operate applications successfully in the cloud. This series will also cover topics on cloud financial management, security, modern data and artificial intelligence (AI), cloud operating models, and strategies for cloud migration.

Optimize cost and performance with AWS services

Your technology costs vs. return on investment (ROI) is likely being constantly evaluated. In the cloud, you “pay as you go.” This means your technology spend is an operational cost rather than capital expenditure, as discussed in Part 3: Cloud economics – OPEX vs. CAPEX.

So, how do you maximize the ROI of your cloud spend? The following sections provide hosting options and to help you choose a hosting model that best suits your needs.

Evaluating your hosting options

EC2 instances and the lift and shift strategy

Using cloud native dynamic provisioning/de-provisioning of Amazon Elastic Compute Cloud (Amazon EC2) instances will help you meet business needs more accurately and optimize compute costs. EC2 instances allow you to use the “lift and shift” migration strategy for your applications. This helps you avoid overhead costs you may incur from upfront capacity planning.

Comparing on-premises vs. cloud infrastructure provisioning

Figure 1. Comparing on-premises vs. cloud infrastructure provisioning

Containerized hosting (with EC2 hosts)

Engineering teams already skilled in containerized hosting have saved additional costs by using Amazon Elastic Kubernetes Service (Amazon EKS) or Amazon Elastic Container Service (Amazon ECS). This is because your unit of deployment is a container instead of an entire instance, and Amazon EKS or Amazon ECS can pack multiple containers into a single instance. Application change management is also less risky because you can leverage Amazon EKS or Amazon ECS built-in orchestration to manage non-disruptive deployments.

Serverless architecture

Use AWS Lambda and AWS Fargate to scale to match unpredictable usage. We have seen AWS software as a service (SaaS) customers build better measures of “cost per user” of an application into their metering systems using serverless. This is because instead of paying for server uptime, you only pay for runtime usage (down to millisecond increments for Lambda) when you run your application.

Further considerations for choosing the right hosting platform

The following table provides considerations for implementing the most cost-effective model for some use cases you may encounter when building your architecture:

Table 1

Building a cloud operating model and managing risk

Building an effective people, governance, and platform capability is summarized in the following sections and discussed in detail in Part 5: Organizing teams to enable effective build/run/manage.

People

If your team only builds applications on virtual machines, asking them to move to the cloud serverless model without sufficiently training them could go poorly. We suggest starting small. Select a handful of applications that have lower risk yet meaningful business value and allow your team to build their cloud “muscles.”

Governance

If your teams don’t have the “muscle memory” to make cloud architecture decisions, build a Cloud Center of Excellence (CCOE) to enforce a consistent approach to building in the cloud. Without this team, managing cost, security, and reliability will be harder. Ask the CCOE team to regularly review the application architecture suitability (cost, performance, resiliency) against changing business conditions. This will help you incrementally evolve architecture as appropriate.

Platform

In a typical on-premises environment, changes are deployed “in-place.” This requires a slow and “involve everyone” approach. Deploying in the cloud replaces the in-place approach with blue/green deployments, as shown in Figure 2.

With this strategy, new application versions can be deployed on new machines (green) running side by side with the old machines (blue). Once the new version is validated, switch traffic to the new (green) machines and they become production. This model reduces risk and increases velocity of change.

AWS blue/green deployment model

Figure 2. AWS blue/green deployment model

Securing your application and infrastructure

Security controls in the cloud are defined and enforced in software, which brings risks and opportunities. If not managed with a robust change management process, software-defined firewall misconfiguration can create unexpected threat vectors.

To avoid this, use cloud native patterns like “infrastructure as code” that express all infrastructure provisioning and configuration as declarative templates (JSON or YAML files). Then apply the same “Git pull request” process to infrastructure change management as you do for your applications to enforce strong governance. Use tools like AWS CloudFormation or AWS Cloud Development Kit (AWS CDK) to implement infrastructure templates into your cloud environment.

Apply a layered security model (“defense in depth”) to your application stack, as shown in Figure 3, to prevent against distributed denial of service (DDoS) and application layer attacks. Part 2: Protecting AWS account, data, and applications provides a detailed discussion on security.

Defense in depth

Figure 3. Defense in depth

Data stores

How many is too many?

In on-premises environments, it is typically difficult to provision a separate database per microservice. As a result, the application or microservice isolation stops at the compute layer, and the database becomes the key shared dependency that slows down change.

The cloud provides API instantiable, fully managed databases like Amazon Relational Database Service (Amazon RDS) (SQL), Amazon DynamoDB (NoSQL), and others. This allows you to isolate your application end to end and create a more resilient architecture. For example, in a cell-based architecture where users are placed into self-contained, isolated application stack “cells,” the “blast radius” of an impact, such as application downtime or user experience degradation, is limited to each cell.

Database engines

Relational databases are typically the default starting point for many organizations. While relational databases offer speed and flexibility to bootstrap a new application, they bring complexity when you need to horizontally scale.

Your application needs will determine whether you use a relational or non-relational database. In the cloud, API instantiated, fully managed databases give you options to closely match your application’s use case. For example, in-memory databases like Amazon ElastiCache reduce latency for website content and key-value databases like DynamoDB provide a horizontally scalable backend for building an ecommerce shopping cart.

Summary

We acknowledge that CTO responsibilities can differ among organizations; however, this blog discusses common key considerations when building and operating an application in the cloud.

Choosing the right application hosting platform depends on your application’s use case and can impact the operational cost of your application in the cloud. Consider the people, governance, and platform aspects carefully because they will influence the success or failure of your cloud adoption. Use lower risk application deployment patterns in the cloud. Managed data stores in the cloud open your choice for data stores beyond relational. In the next post of this series, Part 2: Protecting AWS account, data, and applications, we will explore best practices and principles to apply when thinking about security in the cloud.

Related information

  • Part 2: Protecting AWS account, data and applications
  • Part 3: Cloud economics – OPEX vs CAPEX
  • Part 4: Building a modern data platform for AI
  • Part 5: Organizing teams to enable effective build/run/manage
  • Part 6: Strategies and lessons on migrating workloads to the cloud

Understanding Amazon Machine Images for Red Hat Enterprise Linux with Microsoft SQL Server

Post Syndicated from Emma White original https://aws.amazon.com/blogs/compute/understanding-amazon-machine-images-for-red-hat-enterprise-linux-with-microsoft-sql-server/

This post is written by Kumar Abhinav, Sr. Product Manager EC2, and David Duncan, Principal Solution Architect. 

Customers now have access to AWS license-included Amazon Machine Images (AMI) for hosting their SQL Server workloads with Red Hat Enterprise Linux (RHEL). With these AMIs, customers can easily build highly available, reliable, and performant Microsoft SQL Server 2017 and 2019 clusters with RHEL 7 and 8, with a simple pay-as-you-go pricing model that doesn’t require long-term commitments or upfront costs. By switching from Windows Server to RHEL to run SQL Server workloads, customers can reduce their operating system licensing costs and further lower total cost of ownership. This blog post provides a deep dive into how to deploy SQL Server on RHEL using these new AMIs, how to tune instances for performance, and how to reduce licensing costs with RHEL.

Overview

The RHEL AMIs with SQL Server are customized for the following editions of SQL Server 2019 or SQL Server 2017:

  • Express/Web Edition is an entry-level database for small web and mobile apps.
  • Standard Edition is a full-featured database designed for medium-sized applications and data marts.
  • Enterprise Edition is a mission-critical database built for high-performing, intelligent apps.

To maintain high availability (HA), you can bring the same HA configuration from an on-premises Enterprise Edition to AWS by combining SQL Server Availability Groups with the Red Hat Enterprise Linux HA add-on. The HA add-on provides a light-weight cluster management portfolio that runs across multiple AWS Availability Zones to eliminate single point of failure and deliver timely recovery when there is need.

These AMIs include all the software packages required to run SQL Server on RHEL along with the most recent updates and security patches. By removing some of the heavy lifting around deployment, you can deploy SQL Server instances faster to accommodate growth and service events.

The following architecture diagram shows the necessary building blocks for SQL Server Enterprise HA configuration on RHEL.

instance configuration

To build the RHEL 7 and RHEL 8 AMIs, we focused on requirements from the Red Hat community of practice for SQL Server, which includes code, documentation, playbooks, and other artifacts relating to deployment of SQL Server on RHEL. We used Amazon EC2 Image Builder for installing and updating Microsoft SQL Server. For custom configuration or for installing any additional software, you can use the base machine image and extend it using EC2 Image Builder. If you have different, requirements, you can build your own images using the Red Hat Image Builder.

Tuning for virtual performance and compatibility with storage options

It is a common practice to apply pre-built performance profiles for SQL Server deployments when running on-premises. However, you do not need to apply the operating system performance tuning profiles for SQL Server to optimize the performance on Amazon EC2. The AMIs include the virtual-guest tuning from Red Hat along with additional optimizations for the EC2 environment. For example, the images include the timeout for NVMe IO operations set to the maximum possible value for an experience that is more consistent with the way EBS volumes are managed. Database administrators can further configure workload specific tuning parameters such as paging, swapping, and memory pressure using the Microsoft SQL Server performance best practices guidelines.

SQL Server availability groups help achieve HA and improve the read performance of your database cluster. However, this approach only improves availability at the database layer. RHEL with HA further improves the availability of a SQL Server cluster by providing service failover capabilities at the operating system layer. You can easily build a highly available database cluster as shown in the following figure by using the RHEL with SQL Server and HA add-on AMI on an instance of their choice in multiple Availability Zones.


High availability SQL Cluster built on top of RHEL HA

When it comes to storage, AWS offers many different choices. Amazon Elastic Block Storage (EBS) offers Provisioned IOPS volumes for specific performance requirements, where you know you need a specific level of performance required for the database operations. Provisioned IOPS are an excellent option when the general-purpose volume doesn’t meet your requirements of levels of I/O operations necessary for your production database. EBS volumes add the flexibility you need to increase your volume storage space size and performance through API calls. With Amazon EBS, you can also use additional data volumes directly attached to your instance or leverage multiple instance store volumes for performance targets. Volume IOPS are optimized to be sustainable even if they climb into the thousands, and your maximum IOPS does not decrease.

Storing data on secondary volumes improves performance of your database

Provisioning only one large root EBS volume for the database storage and sharing that with the operating system and any logging, management tools, or monitoring processes is not a well-architected solution. That shared activity reduces the bandwidth and operational performance of the database workloads. On the other hand, using practices like separating the database workloads onto separate EBS volumes or leveraging instance store volumes work well for use cases like storing a large number of temp tables. By separating the volumes by specialized activities, the performance of each component is independently manageable. Profile your utilization to choose the right combination of EBS and instance storage options for your workload.

Lower Total Cost of Ownership

Another benefit of using RHEL AMIs with SQL Server is cost savings. When you move from Windows Server to RHEL to run SQL Server, you can reduce the operating system licensing costs. Windows Server virtual machines are priced per core and hence you pay more for virtual machines with large numbers of cores. In other words, the more virtual machine cores you have, the more you pay in software license fees. On the other hand, RHEL has just two pricing tiers. One is for virtual machines with fewer than four cores and the other is for virtual machines with four cores or more. You pay the same operating system software subscription fees whether you choose a virtual machine with two or three virtual cores. Similarly, for larger workloads, your operating system software subscription costs are the same no matter whether you choose a virtual machine with eight or 16 virtual cores.

In addition, with the elasticity of EC2, you can save costs by sizing your starting workloads accordingly and later resizing your instances to prevent over provisioning compute resources when workloads experience uneven usage patterns, such as month end business reporting and batch programs. You can choose to use On-Demand Instances or use Savings Plans to build flexible pricing for long-term compute costs effectively. With AWS, you have the flexibility to right-size your instances and save costs without compromising business agility.

Conclusion

These new RHEL with SQL Server AMIs on Amazon EC2 are pre-configured and optimized to reduce undifferentiated heavy lifting. Customers can easily build highly available, reliable, and performant database clusters using RHEL with SQL Server along with the HA add-on and Provisioned IOPS EBS volumes. To get started, search for RHEL with SQL Server in the Amazon EC2 Console or find it in the AWS Marketplace. To learn more about Red Hat Enterprise Linux on EC2, check out the frequently asked questions page.


EC2 Image Builder and Hands-free Hardening of Windows Images for AWS Elastic Beanstalk

Post Syndicated from Carlos Santos original https://aws.amazon.com/blogs/devops/ec2-image-builder-for-windows-on-aws-elastic-beanstalk/

AWS Elastic Beanstalk takes care of undifferentiated heavy lifting for customers by regularly providing new platform versions to update all Linux-based and Windows Server-based platforms. In addition to the updates to existing software components and support for new features and configuration options incorporated into the Elastic Beanstalk managed Amazon Machine Images (AMI), you may need to install third-party packages, or apply additional controls in order to meet industry or internal security criteria; for example, the Defense Information Systems Agency’s (DISA) Security Technical Implementation Guides (STIG).

In this blog post you will learn how to automate the process of customizing Elastic Beanstalk managed AMIs using EC2 Image Builder and apply the medium and low severity STIG settings to Windows instances whenever new platform versions are released.

You can extend the solution in this blog post to go beyond system hardening. EC2 Image Builder allows you to execute scripts that define the custom configuration for an image, known as Components. There are over 20 Amazon managed Components that you can use. You can also create your own, and even share with others.

These services are discussed in this blog post:

  • EC2 Image Builder simplifies the building, testing, and deployment of virtual machine and container images.
  • Amazon EventBridge is a serverless event bus that simplifies the process of building event-driven architectures.
  • AWS Lambda lets you run code without provisioning or managing servers.
  • AWS Systems Manager Parameter Store provides secure, hierarchical storage for configuration data, and secrets.
  • AWS Elastic Beanstalk is an easy-to-use service for deploying and scaling web applications and services.

Prerequisites

This solution has the following prerequisites:

All of the code necessary to deploy the solution is available on the . The repository details the solution’s codebase, and the “Deploying the Solution” section walks through the deployment process. Let’s start with a walkthrough of the solution’s design.

Overview of solution

The solution automates the following three steps.

Steps being automated

Figure 1 – Steps being automated

The Image Builder Pipeline takes care of launching an EC2 instance using the Elastic Beanstalk managed AMI, hardens the image using EC2 Image Builder’s STIG Medium Component, and outputs a new AMI that can be used by application teams to create their Elastic Beanstalk Environments.

Figure 2 – EC2 Image Builder Pipeline Steps

Figure 2 – EC2 Image Builder Pipeline Steps

To automate Step 1, an Amazon EventBridge rule is used to trigger an AWS Lambda function to get the latest AMI ID for the Elastic Beanstalk platform used, and ensures that the Parameter Store parameter is kept up to date.

AMI Version Change Monitoring Flow

Figure 3 – AMI Version Change Monitoring Flow

Steps 2 and 3 are trigged upon change to the Parameter Store parameter. An EventBridge rule is created to trigger a Lambda function, which manages the creation of a new EC2 Image Builder Recipe, updates the EC2 Image Builder Pipeline to use this new recipe, and starts a new instance of an EC2 Image Builder Pipeline.

EC2 Image Builder Pipeline Execution Flow

Figure 4 – EC2 Image Builder Pipeline Execution Flow

If you would also like to store the ID of the newly created AMI, see the Tracking the latest server images in Amazon EC2 Image Builder pipelines blog post on how to use Parameter Store for this purpose. This will enable you to notify teams that a new AMI is available for consumption.

Let’s dive a bit deeper into each of these pieces and how to deploy the solution.

Walkthrough

The following are the high-level steps we will be walking through in the rest of this post.

  • Deploy SAM template that will provision all pieces of the solution. Checkout the Using container image support for AWS Lambda with AWS SAM blog post for more details.
  • Invoke the AMI version monitoring AWS Lambda function. The EventBridge rule is configured for a daily trigger and for the purposes of this blog post, we do not want to wait that long prior to seeing the pipeline in action.
  • View the details of the resultant image after the Image Builder Pipeline completes

Deploying the Solution

The first step to deploying the solution is to create the Elastic Container Registry Repository that will be used to upload the image artifacts created. You can do so using the following AWS CLI or AWS Tools for PowerShell command:

aws ecr create-repository --repository-name elastic-beanstalk-image-pipeline-trigger --image-tag-mutability IMMUTABLE --image-scanning-configuration scanOnPush=true --region us-east-1
New-ECRRepository -RepositoryName elastic-beanstalk-image-pipeline-trigger -ImageTagMutability IMMUTABLE -ImageScanningConfiguration_ScanOnPush $True -Region us-east-1

This will return output similar to the following. Take note of the repositoryUri as you will be using that in an upcoming step.

ECR repository creation output

Figure 5 – ECR repository creation output

With the repository configured, you are ready to get the solution. Either download or clone the project’s aws-samples/elastic-beanstalk-image-pipeline-trigger GitHub repository to a local directory. Once you have the project downloaded, you can compile it using the following command from the project’s src/BeanstalkImageBuilderPipeline directory.

dotnet publish -c Release -o ./bin/Release/net5.0/linux-x64/publish

The output should look like:

NET project compilation output

Figure 6 – .NET project compilation output

Now that the project is compiled, you are ready to create the container image by executing the following SAM CLI command.

sam build --template-file ./serverless.template
SAM build command output

Figure 7 – SAM build command output

Next up deploy the SAM template with the following command, replacing REPOSITORY_URL with the URL of the ECR repository created earlier:

sam deploy --stack-name elastic-beanstalk-image-pipeline --image-repository <REPOSITORY_URL> --capabilities CAPABILITY_IAM --region us-east-1

The SAM CLI will both push the container image and create the CloudFormation Stack, deploying all resources needed for this solution. The deployment output will look similar to:

SAM deploy command output

Figure 8 – SAM deploy command output

With the CloudFormation Stack completed, you are ready to move onto starting the pipeline to create a custom Windows AMI with the medium DISA STIG applied.

Invoke AMI ID Monitoring Lambda

Let’s start by invoking the Lambda function, depicted in Figure 3, responsible for ensuring that the latest Elastic Beanstalk managed AMI ID is stored in Parameter Store.

aws lambda invoke --function-name BeanstalkManagedAmiMonitor response.json --region us-east-1
Invoke-LMFunction -FunctionName BeanstalkManagedAmiMonitor -Region us-east-1
Lambda invocation output

Figure 9 – Lambda invocation output

The Lambda’s CloudWatch log group contains the BeanstalkManagedAmiMonitor function’s output. For example, below you can see that the SSM parameter is being updated with the new AMI ID.
BeanstalkManagedAmiMonitor Lambda’s log

Figure 10 – BeanstalkManagedAmiMonitor Lambda’s log

After this Lambda function updates the Parameter Store parameter with the latest AMI ID, the EC2 Image Builder recipe will be updated to use this AMI ID as the parent image, and the Image Builder pipeline will be started. You can see evidence of this by going to the ImageBuilderTrigger Lambda function’s CloudWatch log group. Below you can see a log entry with the message “Starting image pipeline execution…”.

ImageBuilderTrigger Lambda’s log

Figure 11 – ImageBuilderTrigger Lambda’s log

To keep track of the status of the image creation, navigate to the EC2 Image Builder console, and select the 1.0.1 version of the demo-beanstalk-image.

EC2 Image Builder images list

Figure 12 – EC2 Image Builder images list

This will display the details for that build. Keep an eye on the status. While the image is being create, you will see the status as “Building”. Applying the latest Windows updates and DISA STIG can take about an hour.

EC2 Image Builder image build version details

Figure 13 – EC2 Image Builder image build version details

Once the AMI has been created, the status will change to “Available”. Click on the version column’s link to see the details of that version.

EC2 Image Builder image build version details

Figure 14 – EC2 Image Builder image build version details

You can use the AMI ID listed when creating an Elastic Beanstalk application. When using the create new environment wizard, you can modify the capacity settings to specify this custom AMI ID. The automation is configured to run on a daily basis. Only for the purposes of this post, did we have to invoke the Lambda function directly.

Cleaning up

To avoid incurring future charges, delete the resources using the following commands, replacing the AWS_ACCOUNT_NUMBER placeholder with appropriate value.

aws imagebuilder delete-image --image-build-version-arn arn:aws:imagebuilder:us-east-1:<AWS_ACCOUNT_NUMBER>:image/demo-beanstalk-image/1.0.1/1 --region us-east-1

aws imagebuilder delete-image-pipeline --image-pipeline-arn arn:aws:imagebuilder:us-east-1:<AWS_ACCOUNT_NUMBER>:image-pipeline/windowsbeanstalkimagepipeline --region us-east-1

aws imagebuilder delete-image-recipe --image-recipe-arn arn:aws:imagebuilder:us-east-1:<AWS_ACCOUNT_NUMBER>:image-recipe/demo-beanstalk-image/1.0.1 --region us-east-1

aws cloudformation delete-stack --stack-name elastic-beanstalk-image-pipeline --region us-east-1

aws cloudformation wait stack-delete-complete --stack-name elastic-beanstalk-image-pipeline --region us-east-1

aws ecr delete-repository --repository-name elastic-beanstalk-image-pipeline-trigger --force --region us-east-1
Remove-EC2IBImage -ImageBuildVersionArn arn:aws:imagebuilder:us-east-1:<AWS_ACCOUNT_NUMBER>:image/demo-beanstalk-image/1.0.1/1 -Region us-east-1

Remove-EC2IBImagePipeline -ImagePipelineArn arn:aws:imagebuilder:us-east-1:<AWS_ACCOUNT_NUMBER>:image-pipeline/windowsbeanstalkimagepipeline -Region us-east-1

Remove-EC2IBImageRecipe -ImageRecipeArn arn:aws:imagebuilder:us-east-1:<AWS_ACCOUNT_NUMBER>:image-recipe/demo-beanstalk-image/1.0.1 -Region us-east-1

Remove-CFNStack -StackName elastic-beanstalk-image-pipeline -Region us-east-1

Wait-CFNStack -StackName elastic-beanstalk-image-pipeline -Region us-east-1

Remove-ECRRepository -RepositoryName elastic-beanstalk-image-pipeline-trigger -IgnoreExistingImages $True -Region us-east-1

Conclusion

In this post, you learned how to leverage EC2 Image Builder, Lambda, and EventBridge to automate the creation of a Windows AMI with the medium DISA STIGs applied that can be used for Elastic Beanstalk environments. Don’t stop there though, you can apply these same techniques whenever you need to base recipes on AMIs that the image origin is not available in EC2 Image Builder.

Further Reading

EC2 Image Builder has a number of image origins supported out of the box, see the Automate OS Image Build Pipelines with EC2 Image Builder blog post for more details. EC2 Image Builder is also not limited to just creating AMIs. The Build and Deploy Docker Images to AWS using EC2 Image Builder blog post shows you how to build Docker images that can be utilized throughout your organization.

These resources can provide additional information on the topics touched on in this article:

Carlos Santos

Carlos Santos

Carlos Santos is a Microsoft Specialist Solutions Architect with Amazon Web Services (AWS). In his role, Carlos helps customers through their cloud journey, leveraging his experience with application architecture, and distributed system design.