What worried us wasn’t the hallucination, it was the subtle plausibility. Answers an engineer could easily read past and accept: a right-looking Structured Query Language (SQL) query, a plausible tool call, an innocent profile update, or a patch that satisfied the surface tests.
When we analyzed the row-level failures, a clear pattern emerged:
SQL generation: kept the query shape but changed the underlying metric.
Tool calling: selected the right tool family but drifted on parameters.
Profile updates: cited every event instead of only the evidence that supported the claim.
Coding agents: passed visible tests while missing a hidden stateful invariant.
Grab Bench bridges this exact gap. Grab Bench is a configurable eval (evaluation) harness for artificial intelligence (AI) systems on Grab-shaped work. It runs model providers through task plugins, records one row per case/model pair, and uses deterministic scorers or large language model (LLM) judges depending on the task. We treat the eval like software: version it, run baselines, keep score records, and make the failure modes visible enough for a team to debug.
This write-up focuses on the design choices behind that work.
The problem: plausible is not correct
Public leaderboards are still useful; we read them too. They just answer a different question. A product team needs to know whether a model can preserve a metric definition, obey an internal tool contract, stay cautious with weak evidence, or make a code change without breaking behaviour hidden from the prompt.
The hard part is that real examples are rarely reusable as-is. Production traces, schemas, user records, and internal workflows need protection. So the benchmark has to preserve the shape of the work without depending on the work itself.
That constraint shaped Grab Bench from the beginning. Some surfaces stay internal. Others use synthetic or redacted cases. Either way, the case has to keep the thing that makes the work hard: metric faithfulness, tool-parameter discipline, evidence grounding, safety boundaries, or repository-level behaviour.
What Grab Bench runs
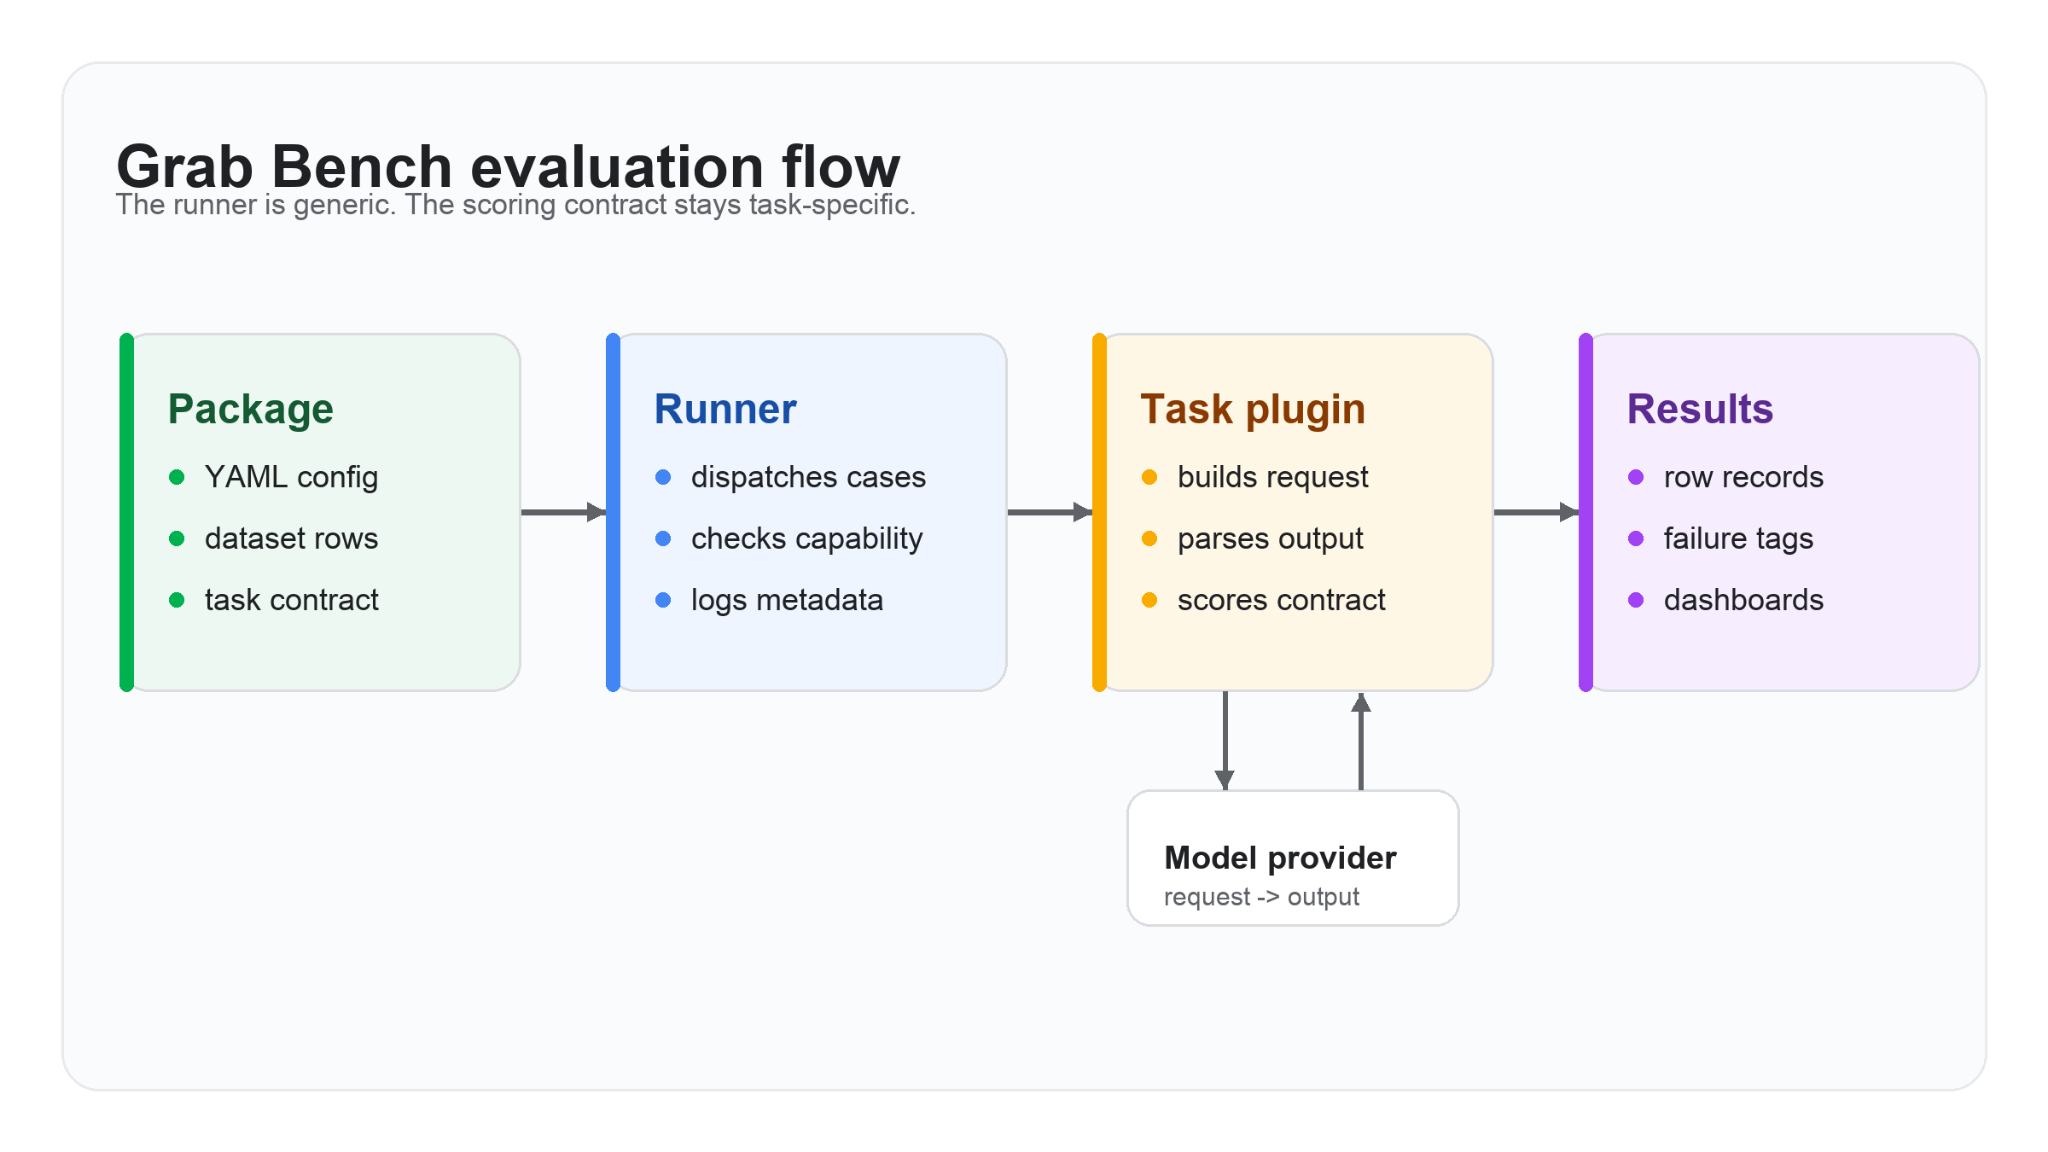
The harness is deliberately ordinary. A YAML configuration defines providers, models, task settings, sampling, concurrency, judge settings, and output paths. The runner loads rows, checks whether each model supports the required modality and application programming interface (API) family, calls the task plugin, and writes row-level records plus model summaries for dashboards.
The unusual part is that each task owns its contract:
Query generation cares about preserving metric and schema intent.
Tool use compares canonical tool names and parameters.
Agentic coding runs visible and hidden workspace tests, plus hard-failure and anti-gaming checks.
This is why the row record matters. A leaderboard can tell us that one model is ahead. It cannot tell us whether the loss came from a fabricated evidence identifier (ID), a weak action, a hidden invariant, latency, cost, or a genuine capability gap.
Each run also keeps the unglamorous fields that make reruns possible: token use, latency, judge latency where applicable, skip reasons, resolved configurations, and dashboard-ready summaries. Without those fields, the next comparison starts from memory instead of evidence.
Figure 1 is deliberately boring: add a plugin; providers, records, and dashboards stay shared.
Figure 1. Grab Bench keeps execution shared while task plugins own request shaping, parsing, and scoring.
Design choice 1: make the cases safe, not generic
A useful eval case should feel familiar to the people who own the system. It should include distractors, stale context, ambiguous evidence, and the kind of boundary conditions that make production work tricky.
In passenger-profile reasoning, each case is a synthetic evidence ledger: rides, food, support, app events, saved places, promotions, and noise. All cases use synthetic data with no live user records. The model must return strict JavaScript Object Notation (JSON). Claims must come from an ontology; values must be valid for that claim; evidence IDs must exist; weak or sensitive inferences should be suppressed, not laundered into confident prose.
The scorer is deliberately mechanical where it can be: schema validity, claim correctness, evidence faithfulness, confidence calibration, action quality, and safety. It distinguishes required claims from acceptable auxiliary claims and forbidden claims, so a model can get credit for useful extra evidence without getting a pass on unsafe or unsupported inferences.
A simplified case might ask whether a passenger has a stable weekday commute:
The evidence ledger contains repeated morning rides from a home-like saved place to an office-like area, plus unrelated food orders and stale support contacts.
A good answer returns a claim such as weekday_commute = likely_home_to_office_commute, cites only the commute evidence IDs, and keeps confidence within the allowed range.
The scorer checks that the claim and value exist in the ontology, that every cited evidence ID exists, and that the cited rows actually support the claim.
If the model cites every event, fabricates an ID, adds a dietary-preference claim from one old order, or recommends an unsafe action, the row gets explicit failure tags or a score cap.
The result is still a number, but the row also says what failed, which is what an engineer needs to fix the prompt, scorer, data, or model choice.
For agentic coding, the repository is synthetic too, but it asks for a real-shaped change: default ride insurance across backend services, API compatibility, mobile helpers, analytics events, rollout controls, migration compatibility, idempotency, concurrency, and cancellation lifecycle. A patch that only satisfies visible tests is not enough.
The safety comes from using synthetic data. The pressure comes from keeping the real contract intact.
Design choice 2: score contracts, not confidence
LLM judges are useful for open-ended tasks such as SQL, where correctness can depend on business intent and query shape. But for many surfaces, the benchmark should not ask another model whether an answer seems good.
Grab Bench uses deterministic scoring when the task contract allows it. Passenger-profile reasoning scores ontology values and evidence IDs. Tool use compares canonical tool names and parameters. Multimodal pair matching scores exact labels. Agentic coding scores visible and hidden tests, maintainability, efficiency, and hard-failure gates.
The audit trail is the point. A fluent answer should not get credit for missing the contract. The row needs to say whether the model misunderstood the task, ignored a constraint, exceeded a budget, or produced something plausible but unsupported.
Design choice 3: make shortcuts visible
Benchmarks get weaker when shortcuts work. The scorer has to make those shortcuts visible.
In the reasoning benchmark, fabricated evidence IDs, unsupported claims, broad cite-everything behaviour, unsafe actions, and forbidden sensitive claims trigger penalties or caps. In the coding benchmark, hidden-test tampering, network-access patterns, oversized patches, case-id leakage, visible-only overfit, and implausible difficulty curves are blocked or investigated.
Baselines make that visible. Empty output, schema-only output, cite-all-evidence output, unsafe-sensitive output, no-op coding agents, and reference agents are not busywork; they are checks on the scorer. If a shortcut baseline can pass, the benchmark is not ready.
This is not about assuming bad faith. It is about refusing to reward behaviour that would fail the moment it left the harness. A profile update that cites every event has not shown evidence discipline. A SQL answer that changes the metric has not preserved intent. A coding agent that passes only visible tests has not earned trust.
Internal reproducibility and hidden pressure
The package has to be inspectable and hard to overfit at the same time. Engineers need to rerun the harness, read score records, and understand failures. Certification still needs unseen cases, or we end up optimising prompts against the examples everyone can see.
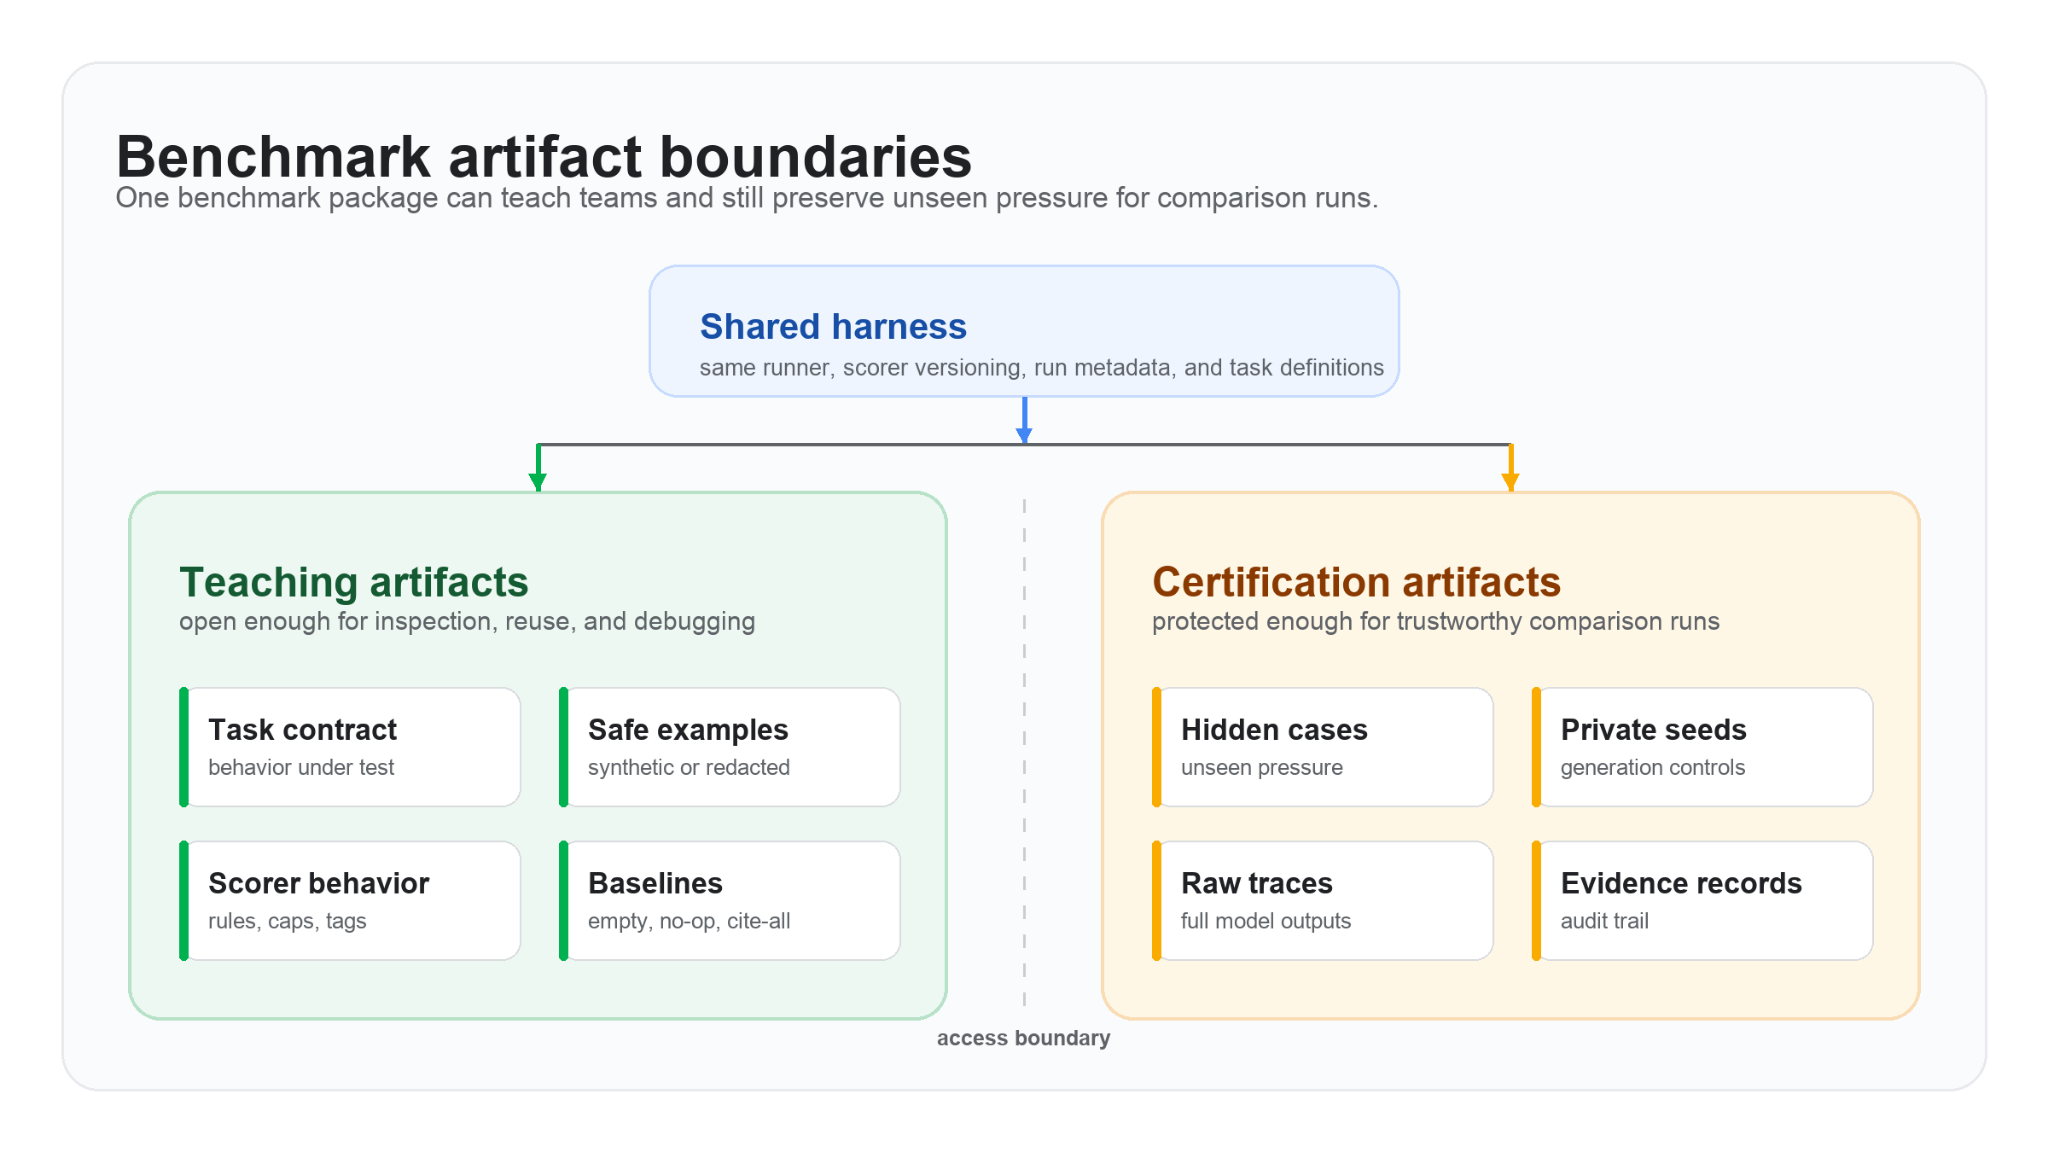
Grab Bench handles this with a split between teaching artifacts and certification artifacts. Teaching artifacts explain the task contract, scorer, examples, baselines, and canaries. Certification artifacts keep hidden splits, seeds, raw outputs, and full comparison evidence behind the right access boundaries.
One dataset cannot do all of that honestly. Shared examples are for learning the method. Hidden cases are for checking generalisation. Row-level outputs are for debugging. Aggregates are for comparison.
Before a comparison run is trusted, the package also has to pass gates: oracle or reference solutions behave as expected, weak baselines fail, redaction passes where applicable, score spread remains useful, and canaries catch harness regressions. Here, a canary is a deliberately simple or malformed case with a known expected result, such as a no-evidence profile update that must be rejected.
Figure 2. Teaching artifacts and certification artifacts share the same harness but need different access boundaries.
What we learned
The most useful Grab Bench output is often not the leaderboard. It is the failure taxonomy.
We saw that more reasoning is not a universal good. It can help planning-heavy tool use and hurt tasks that need literal schema discipline. Evidence selection is also part of reasoning: citing everything is not safer when only a few rows are direct support. For agentic coding, category-level results matter because a model can handle API contracts while missing stateful invariants.
We also learned not to treat prompt or model settings as universal. A setting that helps one task can make another worse. That pushed us toward task-level reports, not one global recommendation, and toward comparisons that show failure tags alongside scores.
Most of all, evals need hygiene: versions, baselines, gates, dashboards, and scope limits.
One limit is worth stating plainly: synthetic evals do not prove production uplift. They tell us whether a model respects the contract under controlled pressure. Live retrieval quality, user impact, and rollout decisions still need separate evidence.
What comes next
Next, we want the benchmark surfaces to look more like pipelines. Instead of scoring only the final answer, we want to separate retrieval, reasoning, action selection, latency, cost, and safety where the task supports it.
We also want packages to be easier for other teams to reuse. A good eval should not depend on one team remembering how it works; it should be documented, versioned, and safe enough for others to run.
Grab Bench is our attempt to make AI evaluation boring in the useful way: configuration in, rows out, failures explained, shortcuts caught. The question is not which model wins in the abstract. It is which model is ready for this work, under these constraints, with these failure modes.
The test I would apply to any eval is simple. If a cite-everything baseline can pass, the eval is not measuring evidence discipline. If a visible-test-only agent can pass, it is not measuring production behaviour. The useful conversation starts when the benchmark can show the shortcut and make it fail.
Join us
Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Java developers no longer have to rely on Java framework-specific approaches to drive AI from their enterprise apps.
While it is true that Langchain4j empowered developers by disintermediating specific AI vendors, you still had a dependency on Langchain4j. And with Spring AI, well, of course you had a dependency on design choices made by Spring, if not on Spring itself.
Now, GitHub Copilot SDK for Java is the first truly framework agnostic way to drive AI from Java. And with its BYOK support, GitHub Copilot SDK for Java is also AI vendor neutral.
💡 Even though it’s called GitHub Copilot SDK, you can use it with any direct model provider, such as OpenAI, Azure, Anthropic, or OpenAI-compatible endpoints, by passing a provider/ProviderConfig with your own baseUrl + apiKey (or bearer token). No Copilot subscription required.
The GitHub Copilot SDK for Java is a client library that empowers your server-side Java code to create Copilot agent sessions, register tools, send prompts, and receive structured responses—all programmatically. It works in server environments, including Jakarta EE and Spring. If you’ve been building enterprise Java for any length of time, this SDK will feel like home: CompletableFuture, annotations, lambdas, virtual threads, it’s all here.
This post shows you how to use the SDK, walks through a complete Jakarta EE 11 sample application, and leaves you with concrete next steps to try it yourself. I chose Jakarta EE 11 for my demo because I was the lead release coordinator for that release. I believe in open standards as the best way to empower developers. For more on Jakarta EE 11 see this InfoQ article.
This sample app is an agent harness using Jakarta EE 11. But, of course, developers can build their own agent harness using the well-known Java frameworks and libraries of their choice.
git clone https://github.com/microsoft/Build26-BRK206-your-agent-anywhere-multiclient-multidevice-with-github-copilot-sdk.git
cd Build26-BRK206-your-agent-anywhere-multiclient-multidevice-with-github-copilot-sdk/src/java-agent-orchestrator
mvn clean package liberty:run
# Open http://localhost:9080/index.xhtml
The Java demo is built on:
Concern
Technology
Runtime
Open Liberty 26.0.0.5
Platform
Jakarta EE 11 (Faces 4.1, CDI 4.1, WebSocket 2.2, Data 1.0, Persistence 3.2)
UI
PrimeFaces 15.0.16
AI orchestration
Copilot SDK for Java 1.0.7-preview.1
Database
H2 in-memory (10 seed property listings)
What the app does
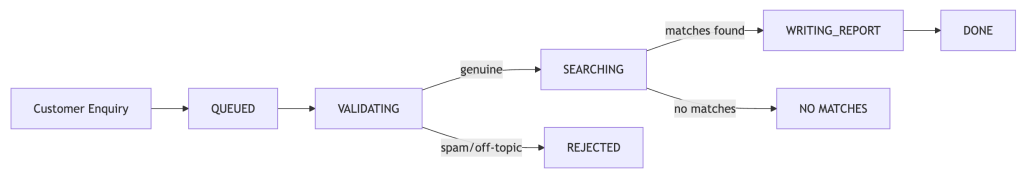
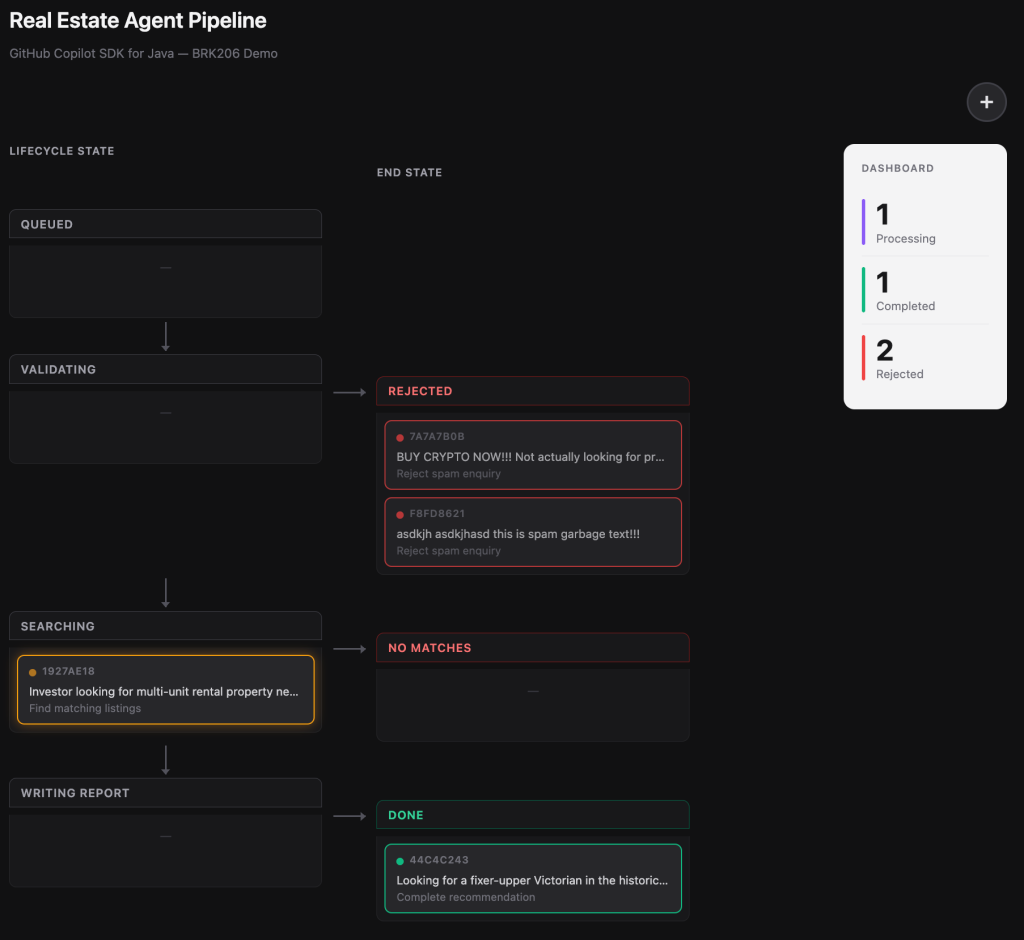
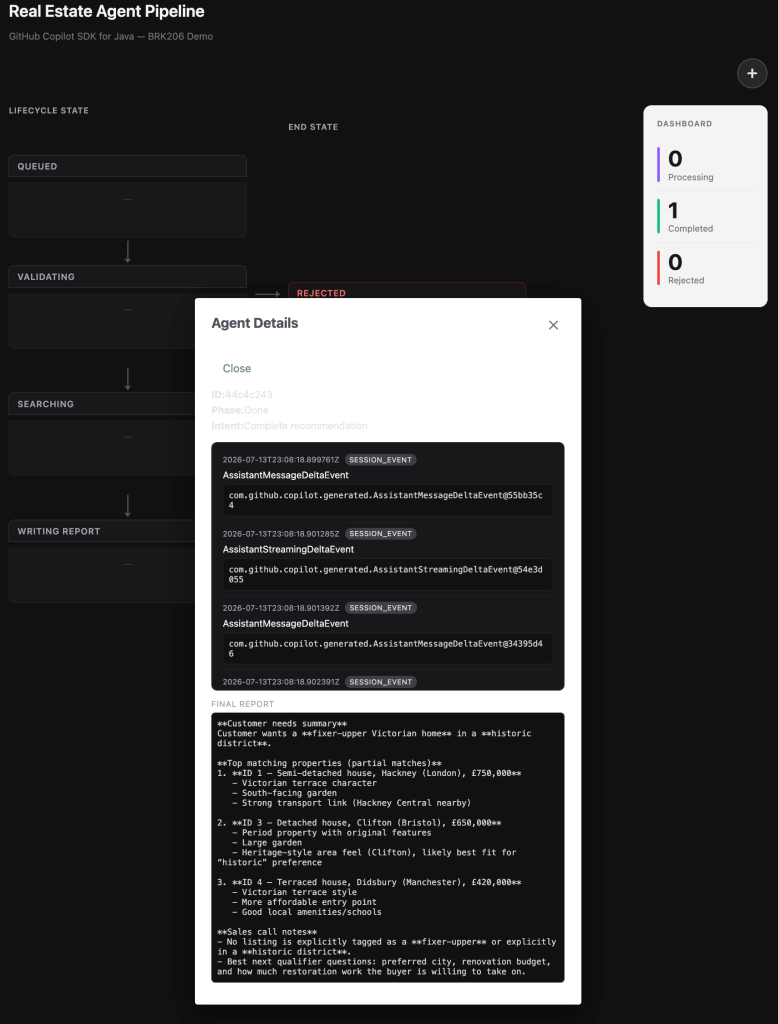
The application is a real-estate lead-management agent pipeline. A customer submits an enquiry (“I’m looking for a 3-bedroom house in London under £800,000”), and the system spins up an isolated Copilot Agent on a virtual thread to process it through a pipeline:
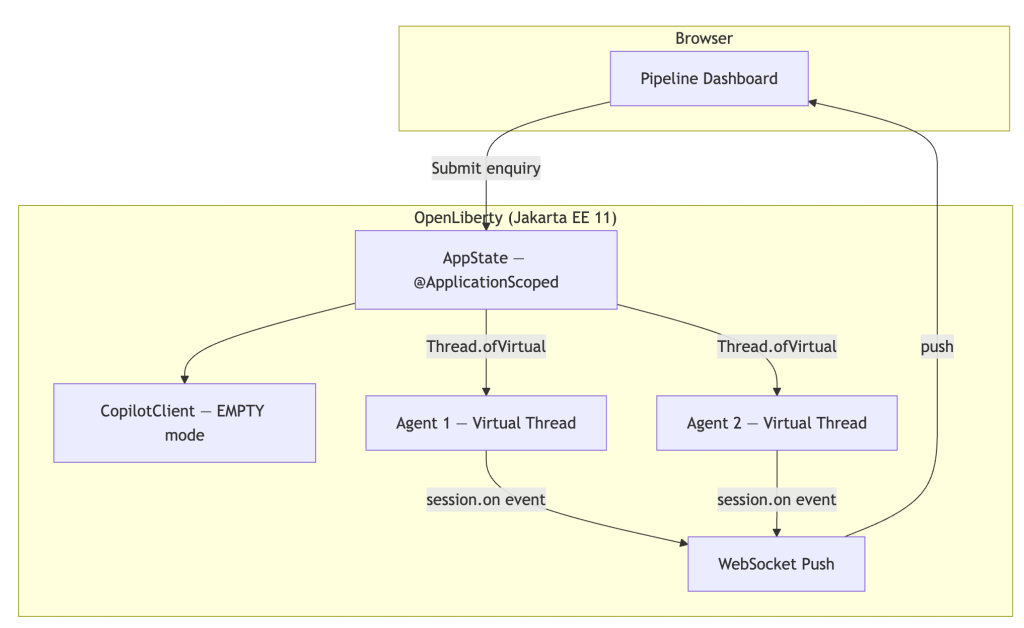
The architecture uses Jakarta WebSocket to push real-time status updates from the server to the browser, so you can watch agents progress through phases as the model calls tools:
Submit multiple inquiries simultaneously to see concurrent virtual-thread agents in action. Each one processes independently with its own Copilot session.
SDK features in action
Let’s walk through the key SDK features as they appear in the sample code.
Defining tools with @CopilotTool
This is the headline API. If you’ve ever written a @GET endpoint in JAX-RS or an @MessageDriven bean, this will feel instantly familiar:
@CopilotTool(value = "Sets the current phase of the agent. Use this to report progress.",
             name = "set_current_phase")
public String setCurrentPhase(
        @CopilotToolParam("The phase to transition to (VALIDATING, SEARCHING, "
                + "WRITING_REPORT, REJECTED_GARBAGE, REJECTED_NO_MATCHES, or DONE)")
        String phaseName) {
    phase = Phase.valueOf(phaseName.trim().toUpperCase(Locale.ROOT));
    notifyUi();
    return "Phase set to " + phase.getLabel();
}
The @CopilotTool annotation declares the method as a tool the model can call. The @CopilotToolParam annotation describes each parameter so the model knows what to pass. The SDK handles all the JSON Schema generation, argument parsing, and dispatch. You just write a normal Java method.
Two build prerequisites for @CopilotTool. The annotation-based tool API is currently an experimental feature of the SDK, so you need to configure two things in your Maven build:
Enable experimental APIs: pass -Acopilot.experimental.allowed=true to the compiler. Without this flag, the annotation processor will refuse to generate the tool metadata. For more details on the experimental APIs see Copilot SDK documentation.
Register the annotation processor: add the SDK as an annotationProcessorPath so the compiler can find the @CopilotTool processor and generate the $$CopilotToolMeta classes at compile time.
When you want a tool defined at the call site without a dedicated method, use the lambda style:
ToolDefinition reportIntentTool = ToolDefinition
        .from("report_intent",
              "Reports the current intent of the agent",
              Param.of(String.class, "intent", "Intent in max 4 words"),
              (String intent) -> {
                  currentIntent = intent;
                  addEvent(Instant.now(), "intent", "Intent updated", intent);
                  notifyUi();
                  return "ok";
              })
        .overridesBuiltInTool(true);
Notice .overridesBuiltInTool(true). This tells the SDK that our report_intent tool deliberately replaces a built-in tool of the same name. This is useful when you need custom behaviour for a tool the model already knows about.
Cross-class tool scanning
Tools don’t have to live in the same class as your agent logic. Here’s searchProperties defined in a separate CDI bean:
@ApplicationScoped
public class PropertyDatabase {

    @CopilotTool(value = "Searches the real estate listings database. "
                       + "Returns up to 10 matching properties.",
                 name = "search_properties")
    public List<Property> searchProperties(
            @CopilotToolParam("Property type substring (e.g. 'flat', 'house')") String type,
            @CopilotToolParam("City substring (e.g. 'London', 'Bristol')") String city,
            @CopilotToolParam("Minimum number of bedrooms (0 for no minimum)") int minBedrooms,
            @CopilotToolParam("Maximum price in GBP (0 for no maximum)") double maxPriceGbp) {
        // ... filter and return matching properties ...
    }
}
You would normally register these with ToolDefinition.fromObject(propertyDatabase). In the sample app, we use a lambda wrapper instead, because CDI client proxies can obscure the annotation metadata.
Customizing the system message
The SDK gives you fine-grained control over the system message. Use SystemMessageMode.CUSTOMIZE to replace specific sections while preserving the rest:
SystemMessageConfig systemMessage = new SystemMessageConfig()
        .setMode(SystemMessageMode.CUSTOMIZE)
        .setSections(Map.of(SystemMessageSections.IDENTITY,
            new SectionOverride()
                .setAction(SectionOverrideAction.REPLACE)
                .setContent("""
                    You are part of a real estate recommendation system.
                    You will receive enquiries from customers, and you must
                    carry out the following workflow...
                    """)));
The text block ("""...""") makes multi-line prompts readable without string concatenation. The IDENTITY section override replaces only the model’s self-description while leaving safety guardrails intact. If you prefer a simpler approach, SystemMessageMode.APPEND adds your content after the default system message without replacing anything.
The agentic loop: sendAndWait(...)
One line kicks off the full agentic loop:
session = client.createSession(sessionConfig).get();
// ...
AssistantMessageEvent result = session.sendAndWait(escapedEnquiry).get();
Behind .get(), the model reasons, calls your tools (potentially multiple times), and returns its final response. On a virtual thread, .get() is cheap. No platform thread is consumed while waiting. The SDK dispatches tool calls to your registered handlers automatically and feeds results back to the model until it’s done.
Real-time event handling with session.on(...)
Subscribe to session events to build responsive UIs:
Every tool call, every result, every assistant message fires an event. The sample app captures these events and pushes them to the browser via Jakarta WebSocket, so the pipeline dashboard updates in real time. You can use pattern matching to handle specific event types:
if (event instanceof AssistantMessageEvent msg) {
    finalReport = msg.getData().content();
} else if (event instanceof ToolExecutionStartEvent start) {
    // Tool is being invoked...
}
Headless client and permission handling
The client is configured for server-side operation:
copilotClient = new CopilotClient(
        new CopilotClientOptions()
                .setMode(CopilotClientMode.EMPTY)
                .setCopilotHome(copilotHome)
                .setExecutor(contextualVirtualThreadExecutor));
CopilotClientMode.EMPTY means no IDE integration — the client talks directly to the Copilot CLI. The custom Executor (discussed below) ensures tool callbacks run with container context.
APPROVE_ALL is appropriate for demos and development. In production, implement a real permission policy that validates which tools the model is allowed to invoke.
Jakarta EE integration patterns
The SDK is not a framework island. It composes naturally with Jakarta EE — and of course also with proprietary frameworks such as Spring.
The Executor parameter is the key integration point. Jakarta Concurrency (§5.2 in the 3.1 spec) requires that application-created threads be obtained from a ManagedThreadFactory so the container can:
Track the thread for lifecycle shutdown (@PreDestroy / server stop)
And use it to create the Executor we pass to the Copilot SDK.
// The ManagedThreadFactory (virtual=true) creates container-managed virtual
// threads that automatically propagate CDI, JNDI, and transaction context.
Executor managedVirtualExecutor = runnable ->
    virtualThreadFactory.newThread(runnable).start()

String copilotHome = Path.of(System.getProperty("user.home"), ".copilot").toString();
CopilotClientOptions copilotClientOptions = new CopilotClientOptions()
        .setMode(CopilotClientMode.EMPTY)
        .setCopilotHome(copilotHome)
        .setExecutor(managedVirtualExecutor);
copilotClient = new CopilotClient(copilotClientOptions);
This creates virtual threads that carry the container’s context. When the SDK dispatches a tool call to searchProperties(), that method can @Inject a JPA repository and query the database, because the container context is present on the callback thread.
Other integration patterns in the sample:
CDI @ApplicationScoped for the singleton CopilotClient (one client per application lifecycle).
Jakarta Faces f:websocket push for real-time browser updates via PushContext.
Jakarta Data @Repository for type-safe database queries without raw JPA boilerplate.
Fine-grained tool access control with ToolSet. The SessionConfig lets you specify exactly which tools each session can access:
sessionConfig.setAvailableTools(new ToolSet()
        .addCustom("*")           // all registered custom tools
        .addBuiltIn("web_fetch")); // only the web_fetch built-in
This is an important production concern. Rather than exposing every built-in tool (file system access, shell execution, etc.), you explicitly opt in to only what the agent needs. In the sample app, we allow all custom tools plus web_fetch so the agent can look up real-time property information during the Search phase.
Summary
Here’s what we covered:
Java-native API: CompletableFuture, annotations, lambdas, and virtual threads make the SDK feel like idiomatic Java, not a ported-from-another-language afterthought.
Three tool-definition styles: annotations for enterprise patterns, lambdas for inline convenience, JSON Schema for full control.
System message customization: section-level overrides give you precise control over agent behaviour.
The agentic loop in one line: sendAndWait(...) handles the full tool-calling loop automatically.
Real-time event streaming: session.on(...) enables responsive UIs and observability.
Headless server-side operation: no IDE required; runs anywhere the Copilot CLI is available.
Natural composition with Jakarta EE: CDI, JPA, WebSocket, and virtual threads all work together through the Executor integration point.
What to try next
Explore the BYOK support. The GitHub Copilot SDK can be used directly against model providers, for example OpenAI, Azure, Anthropic, or OpenAI-compatible endpoints, by passing a provider/ProviderConfig with your own baseUrl + apiKey (or bearer token). No Copilot subscription required.
Clone the sample app and run it locally. Submit multiple enquiries simultaneously to see virtual threads in action.
Swap the model. Try session.setModel(...) to experiment with different Copilot models.
Add your own tool. Define a new @CopilotTool method (a mortgage calculator, a school-district lookup) and watch the agent discover and use it.
Deploy to Azure. Open Liberty runs great on Azure App Service, AKS, or Azure Container Apps. See the Jakarta EE on Azure guidance at https://aka.ms/java/ee.
The Copilot SDK for Java puts the full power of GitHub Copilot behind your Java code with no IDE required and no framework lock-in.
Think about the last big feature you shipped. Be honest. Did you cram it into one giant pull request, or did you split it into smaller scoped pull requests? For years, you have silently had to decide between watching a pull request grow so large that reviewing it becomes a nightmare or breaking it into a chain of smaller pull requests that you have to babysit, sync by hand, and untangle conflicts every time a change is introduced below.
Both options have trade-offs. One is hard to review, while the other is hard to maintain. Your decision that day leans towards the less painful option.
Now add coding agents. They are incredibly productive and are projected to drive a 50% productivity gain across every SDLC stage by 2028,according to Gartner. But, they can’t take away the choice of how you structure your pull requests. They amplify the need to make it.
In this post, follow along with an example of how you can use stacked pull requests to simplify reviews.
A closer look: Adding product search to a shopping assistant
Let’s say you issue a prompt to add product search to a shopping assistant, walk away and minutes later, literally, you come back to review, steer, and approve. But look closely at what tends to land in that single pull request:
A new data model and its seed data
An API route and its validation
The client wiring and the UI and the empty/fallback/error states
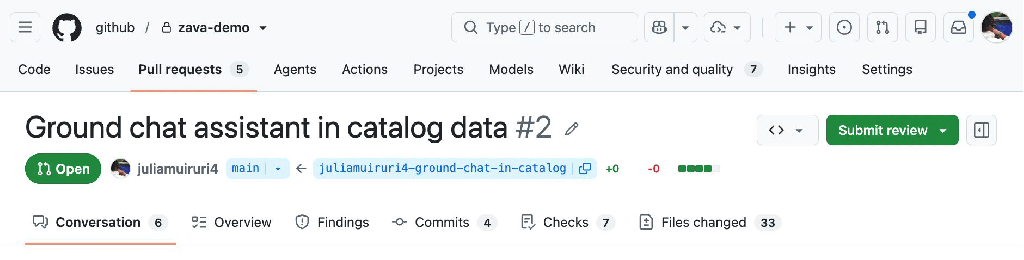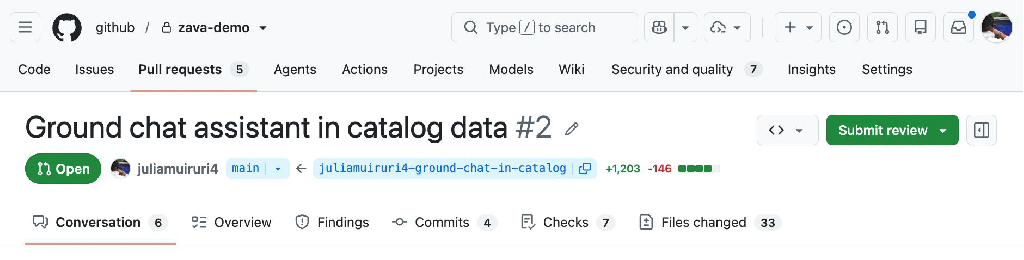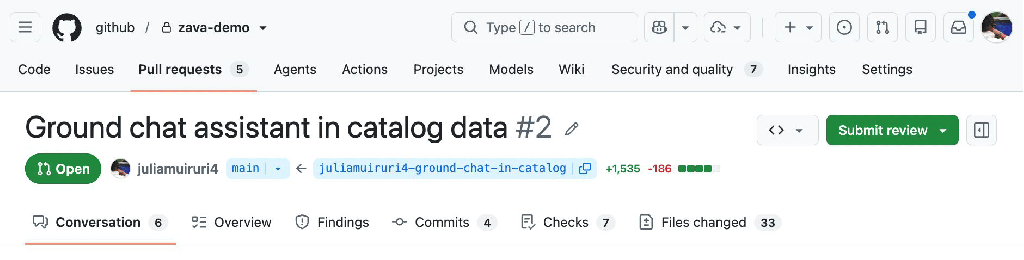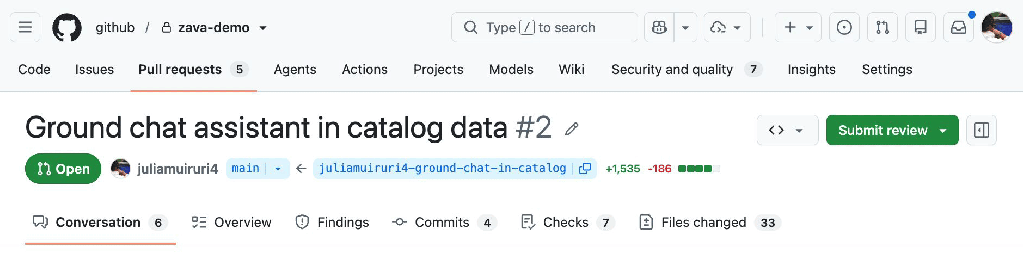
…all of this and more in one ginormous 1,000+ line diff.
For agents largely trained on how code has traditionally been written over the years, this pattern is their default way of shipping. Let’s play this out.
You want to add product search on as existing web application and your starting state is:
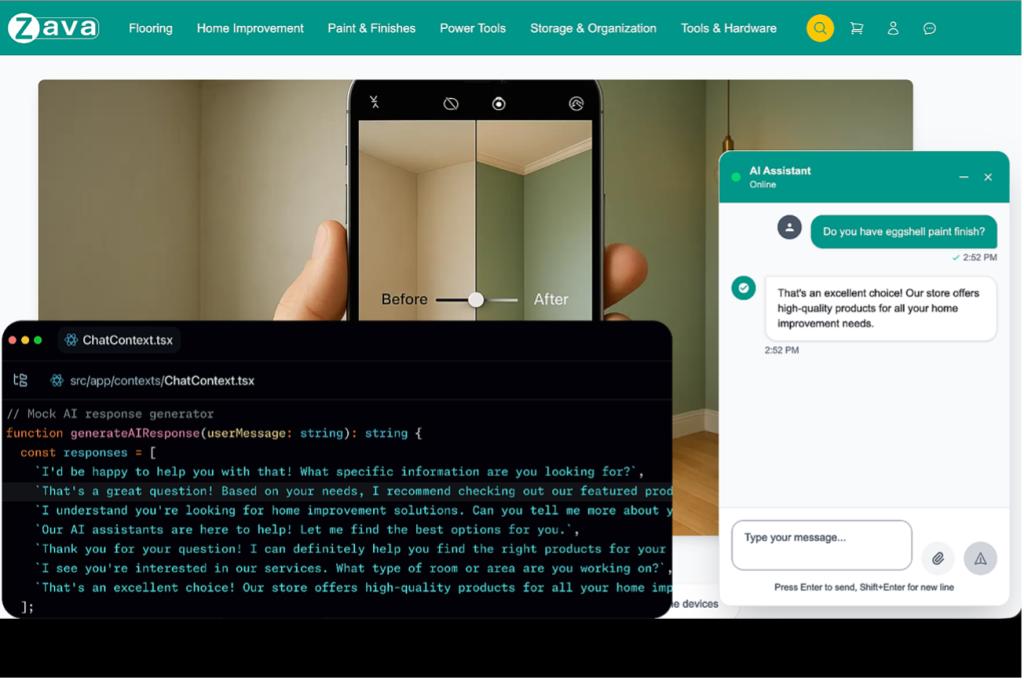
A mock AI Assistant showing responses from a random-line generator
Inconsistent product data hardcoded and scattered across components
No catalog module, no API, no data layer—no nothing
An issue is opened to implement the feature, and a typical flow would be to create a feature branch, assign it to a coding agent (or multiple custom agents), get a first draft of the whole implementation code and updated tests…
…you read the code (well, you maybe read the code). Then, you still need to manually verify feature behavior and make any necessary updates, push and open a pull request with its long-yet-shallow AI generated description, ensure CI checks are green, and self-review diff then request reviewers. You get started…
<reviewer's hat>
Reviewer: 1,721 lines changed!! This description isn’t very helpful. I’ll review this later.
</reviewer's hat>
And what follows is familiar:
The large pull request becomes hard to review—so it just…sits there.
Reviewers lose context and the feedback quality drops.
It becomes even slower to merge.
This kicks off a manual, messy, time-consuming process that’s prone to conflicts before the feature lands, and it eventually lands under-reviewed.
GitHub stacked pull requests
Stacked pull requests introduce a different and better structure of delivery. The principle is simple: decomposition. Instead of shooting for a single pull request that addresses the issue in its entirety, you break down the feature into logical layers and identify the dependency chain to arrive at your desired goal. This gives you, and your agents, a native way to decompose work that otherwise lands in a giant pull request into a chain of small, focused and independently reviewable layers.
That large pull request that’s hard to review becomes a stack of smaller, logically ordered pull requests, each scoped to a single concern, small enough to hold in a reviewer’s head and with just enough context naturally flowing from the previously reviewed pull request.
Let’s make it happen.
The stack structure
Let’s look at the steps involved when decomposing the problem and arranging the layered stack.
First, and importantly, set the stack base. This matters because CI checks and merge rules throughout the stack management lifecycle get evaluated against the stack base.
Then, identify the core foundational unit of work and put it closer to the base (lowest in the stack), and layer dependent work above it.
Stack Layer (L#)/Branch
What to ship
Depends on
L1 (feat/catalog-data)
A typed catalog with seed data, validation, and a data access module
main (stack base)
L2 (feat/search-api)
Validated /api/products/search endpoint
feat/catalog-data
L3 (feat/chat-grounding)
Chat calls the API and answers from real product data
feat/search-api
L4 (feat/grounded-ui)
Product citation cards + state
feat/chat-grounding
Now the independent concerns are clear: data, API, wiring, UX, making it possible to allocate different reviewer audiences for each. Data is reviewed by a data owner, UX by a UI owner.
GitHub’s native support for stacked pull requests can be launched from the pull request UI and extends seamlessly to the terminal with the gh stack CLI.
Install the stacked pull requests CLI extension
Run the following:
gh extension install github/gh-stack
In ancient times, you’d be set to start working. Not today though. There are agents working alongside you. These agents need to learn how stacks work and how to create and manage them on your behalf. The gh-stack skills teaches them this.
gh skill install github/gh-stack
Or, if you prefer:
npx skills add github/gh-stack
For the specific feature from the above example, your development workflow has custom agents, each with defined work streams and that follow a strict scoping discipline to achieve the goal of small, single-scoped pull requests.
Layer/branch
Agent
L1 (feat/catalog-data)
Data modeler agent
L2 ( feat/search-api)
Backend agent
L3 ( feat/chat-grounding)
Frontend agent
L4 ( feat/grounded-ui)
Frontend agent
The last piece of the setup is to confirm CI exists. As mentioned earlier, each pull request will be evaluated against the stack base, and these checks will run for every layer.
Now the work begins.
Layer one: Data catalog foundation
Most agent workflows today are automated and execute autonomously in loops, but for the sake of illustration, we’ll cover each step at a time.
At this point, all agents are familiar with how stacked pull requests work, so a typical workflow at this stage would be:
Invoking the Data Modeler agent with an appropriate prompt
The agent initializes a new stack and sets the first branch—feat/catalog-data with main as its base using gh init stack
Checks out, works and runs validation
(All checks == green) ? commit the layer : Iterate
Reviewer’s note for the future: Are the types correct? Is the data validated? Is the query helper safe? Period.
Layer two: Product search API
Follow a flow similar to:
Invoking the Backend agent with an appropriate prompt
The agent adds the next layer feat/search-apion top of layer one, its base: feat/catalog-data, to import the completed data access module with gh stack add
Checks out, works and runs validation
Developer tests the API manually
(API works && All checks == green) ? commit the layer : Iterate
Reviewer’s note for the future: Is input validated? Is the response contract stable? Are error/empty states handled here or pushed downstream? Period.
Layer three: Wire chat to the API
In this next layer, you:
Invoke the Frontend agent with an appropriate prompt
The agent adds the next layer feat/chat-groundingon top of layer two. Its base: feat/search-api, which will branch off with both the data access module and validated API.
Checks out, works and runs browser tests with Playwright
(All checks == green) ? commit the layer : Iterate
Reviewer’s note for the future: Is every answer tracing back to a real API response? What happens when the API fails or returns nothing? Period.
Layer four: Grounded UI and citations
You’ll notice that layer three and layer four, despite having the same author, (Frontend agent), are layered distinctively. This is deliberate. The UI owner should not have to check the underlying data flow and vice versa, and this structure allows for that independence.
So, the frontend agent:
Adds the next layer feat/grounded-uion top of layer three, its base: feat/chat-grounding
Checks out, works and runs browser tests with Playwright
(All checks == green) ? commit the layer : Iterate
Reviewer’s note for the future: Does every citation link back to a real product? Are loading, empty and error states all covered? Period.
Submit the stack
The four local stacked branches are ready. Next is to push them to remote with gh stack push, then create pull requests linking them on GitHub with gh stack submit.
The stack map and CI on each layer
Switching over to GitHub, all four pull requests are open and at the top of each one, you see a stack map, which is a one-click navigation system between pull requests in the stack.
Reviewing and updating the stack
Time to switch hats and look at a reviewer’s journey through stacked pull requests.
<reviewer’s hat on>
The stack map is a reviewer’s compass – a navigation aid between the top of the stack and its bottom, heading towards a successful merge. The movement is directional: read top-down, review bottom-up.
Read top-down, for context. This gives you the end goal at the very beginning of the review process, so you can set a bearing. “Oh, so we want to display product cards on the chat interface.”
Review bottom-up to build on the predetermined checkpoints. The implementation on each layer only makes sense once the preceding layer is understood.
You are no longer looking at a single 1,720+ line-sized pull request to be reviewed in one sitting, as we saw in our example, but instead, the review can be distributed in small, self-contained targets in a stack.
As the assigned human in the loop reviewer, you come in and look at layer one, the pull request at the bottom of the stack, and see that the automatic Copilot Code Review (CCR) caught two issues which you agree should be fixed.
<developer's hat back on>
Changes are requested at the bottom of the stack, so you:
Hand the feedback to the layer one author, data modeler agent that owns the branch
Suggestions are applied, tested, committed and pushed
Once the fix lands on feat/catalog-data, the natural next question is: what does this mean for layers two, three, and four?
Since branch feat/catalog-data was pushed out of turn after the review, GitHub flags it plainly: “Some branches in this stack have diverged and must be rebased” paired with “Unable to merge as a stack” flag and that blocks the merge.
Back on the pull request UI on GitHub, a one-click Rebase stack button appears. Before using the button, there is something important worth noting. Triggering a web-based rebase using this button runs it on GitHub’s servers, which means it resets the committer to whoever clicked the button, the resulting commits aren’t signed, and if branch protection expects signed commits, that one click quietly breaks.
The safer, equivalent move from the terminal would be gh stack rebase to perform that same cascading rebase locally as you interactively resolve conflicts, but this time using your own Git configuration, then gh stack push.
Finally, you’ll propagate through the stack. The rest of the stack, both local and on GitHub, now needs to catch up, and it couldn’t be easier than a single sync command gh stack sync.
An all-in-one flow starts with fetching from origin, cascading a rebase of every branch above feat/catalog-data onto the new commit, pushes the rebased branches and syncs pull request state from GitHub. This way, the change ripples upward without anyone touching layers two, three, or four by hand.
Back on GitHub, all checks re-run, pass and the stack map settles back into a clean, mergeable line from main to feat/grounded-ui.
Agents Week is about the shift already underway: agents write code, deploy Workers, and provision infrastructure on your behalf. That shift changes what you need to see. If a program is spending money in your Cloudflare account, you need to know what it's spending; throughout the day, per product, in a shape another program can consume. The dashboard is the right answer for humans. It's not the right answer for automation.
So we're launching a new Billable Usage API for self-serve accounts: a single endpoint that returns your account's usage and cost, broken down by product and by service period. It covers every usage-based Cloudflare product on the account, including Workers, R2, D1, Workers AI, Vectorize, Images, and Stream, all with one call. And if you already work in a FinOps toolchain, the column names should look familiar.
You'll get back an HTTP 200 OK with Content-Type: application/json and the usage rows in the response body. Today, usage and cost data are updated daily while we work towards providing more real time data.
What comes back
Each row in the response is one charge period for one product on your account.
ServiceName and ServiceFamilyName — which product ("Workers Standard" under the "Workers" family, "R2 Storage" under "R2", etc.).
ChargePeriodStart / ChargePeriodEnd — the window this row covers.
PricingQuantity and ConsumedUnit — how much you used, in the unit of measure we bill on (GB-months, GB-seconds, requests, etc.).
ContractedCost — what that period cost, in BillingCurrency.
CumulatedPricingQuantity and CumulatedContractedCost — running totals for the billing period.
ZoneId / ZoneName — when the usage is attributed to a specific zone.
Most of these map directly to columns in the FinOps Open Cost and Usage Specification (FOCUS), so if your team is already ingesting FOCUS data from another provider, the names and semantics should be familiar:
Responses use the standard Cloudflare API envelope — result is an array of rows, one per product per charge period, alongside success, errors, and messages.
Where we are on FOCUS
Matching FOCUS naming was a deliberate choice. AWS, Azure, Google Cloud, Oracle, and a growing list of SaaS providers already publish FOCUS formatted exports, and every serious cost-management tool speaks to it. That said, we're not yet claiming full conformance: a handful of columns the spec requires aren't in the payload today. Getting there is on our roadmap. Consider this the first step: familiar shape now, full conformance next.
Cloudflare spend, next to the rest of your cloud spend: our partnership with Vantage
We've partnered with Vantage on a native Cloudflare integration. Vantage is an infrastructure cost management platform that ingests cost and usage data from more than 30 providers, across AI, Cloud and SaaS providers, and brings it into a single view for reporting, allocation, and optimization. With this integration, your usage flows into the same Cost Reports, Budgets, and Cost Alerts you already use for the rest of your infrastructure.
Vantage connects to Cloudflare using a read-only API token with Billing Read access. Once connected, Vantage pulls your Billable Usage data daily and breaks it down by product (such as Workers and R2), zone, and account, so you can see which products drive your spend and attribute it to the teams and services behind it.
A few of the workflows this integration supports:
Cross-provider allocation. Group Cloudflare spend by product, zone, and account, then use Virtual Tags to allocate by team or product line alongside your AWS, Azure, and other provider costs, all in a single report.
Anomaly detection. Vantage Cost Alerts monitor every connected provider and notify you via Slack or E-Mail when spend deviates from its baseline, so a change in Workers or R2 spend surfaces the same way it does for any other provider.
FinOps agents and MCP. Ask the in-console Vantage FinOps agent a question such as "What was our biggest cost driver last week across every provider?", or query the same data from Claude or ChatGPT through Vantage's hosted MCP server. Cloudflare spend is included alongside your other connected providers.
Connect your Cloudflare account in the Vantage console, and your costs appear next to everything else you run. There are no manual exports, no invoice uploads, and no separate dashboard to maintain.
This FOCUS standardized API also works with other Fintech tooling.
Why we built this
Agents do more than write code. They deploy Workers, provision R2 buckets, and manage D1 databases. When you grant programmatic access to your Cloudflare account, you need programmatic visibility into what it's costing you. Not at the end of the month, but throughout the day, by product, in a shape a program can actually consume.
The Billable Usage API is that shape. And customers have been asking us for programmatic usage for years. Finance teams want to pull spend into their own systems and attribute cost back to internal projects, teams, and even their end customers. Developers want a curl they can drop in a script. Every one of those workflows used to involve a screenshot or a manual export. Now it's an HTTP call, or a configuration in Vantage.
What's next
Finer-grained time windows. Today the API returns charge-period rows, which for most products is daily. We're looking at more real time breakdowns for the products where it makes sense.
Forecasting.CumulatedContractedCost tells you where your spend is in the current billing cycle. We want to help you predict where you're going to end up. And not just at the account level, but the product level.
Enterprise coverage. This first release is self-serve only. An equivalent experience for Enterprise contracts is in the works.
Try it
The endpoint is live today for all self-serve accounts. Grab an API token with the Billing Read permission, point your curl at it, and you'll get back your current billing period broken down by product. Full reference is available on the Cloudflare API docs. To see it alongside the rest of your cloud spend, connect your Cloudflare account in the Vantage console.
Cloudflare has spent years making it easy to run more of your stack on our network. It's time we made it just as easy to see what that's costing you — on Cloudflare, and everywhere else.
At Grab, analytics sits close to almost every decision that matters. Our north star is the democratisation of intelligence, ensuring that anyone making a business call has immediate access to trustworthy answers.
Over the last two years, model capability has crossed a threshold enabling this shift. Agents now do in minutes what used to take a week: preparing the data, writing queries, running deep analysis and developing insights for business opportunities, designing experiments and interpreting the results, drafting the commentary that follows, and more. Our throughput is no longer rate-limited by how fast an individual can write code, build a deck, or run a deep-dive. It is rate-limited by how fast we can frame the right problem, judge the right answer, and influence the right decision.
As autonomy climbs, an analyst’s impact moves from producing the artefact to owning the question and the call behind it, and the role evolves to become part builder, part advisor, part strategist, owning the loop rather than running it. That unlocks two things at once: work we already do, faster and at lower marginal cost, and work we could never staff before, sitting beside every product manager, business owner, and operator at the moment they decide.
The ladder
We were heavily inspired by Dan Shapiro’s framing of five levels for AI coding. We use a similar ladder that defines how much of the loop an agent should own and where human judgement stays for every analytics loop.
One distinction runs across every level: who owns the loop, and where human judgement is required.
Level
What
Human role
Agent role
L2
AI-Assisted
Owns and executes every step; uses AI to draft, suggest, summarise
Drafts SQL, suggests a visualisation
L3
Human plans, agent owns steps, human reviews
Frames the question, picks the metric, the segment, and the comparison frame, reviews evidence, owns the recommendation
Discovers data, writes and runs the query, sanity checks, drafts the write-up, flags caveats
L4
Agent plans, agent owns workflows, human reviews
Sets intent and guardrails; reviews at gates (anomaly, novel scope, sensitive cut); owns the stakeholder relationship and sign-off
Orchestrates discovery through query, analysis, validation, narrative and publish; runs validation, escalates exceptions
Detects anomalies and opportunities, runs the loop, surfaces insight, evolves the metric layer, context and skills
Human judgement remains at every level, and autonomy never removes accountability. Humans own problem framing, canonical metric definitions, the causal story behind a move, business-case assumptions, the go/no-go, and the stakeholder relationship. A higher level means more of the mechanical loop sits with the agent and more human attention concentrates on the ambiguous, high-stakes work.
Making the climb
Five core capabilities move a workflow up the ladder. They also gate the climb in order: L3 needs execution and certified context, L4 needs gates and agentic review good enough that reviewing only at gates is honest, L5 needs a learning loop that closes.
Execution: A stack that runs the loop end to end rather than a notebook/workflow a human drives.
Knowledge: Metrics certified at the right grain, discoverable in our catalogue, grounded in context an agent can read. Ambiguous definitions cause most analytics slop.
Control: Repeatable expectations become mechanical checks, while human review handles what a rule cannot.
Review and governance: Agents check their own output against the gates and escalate on defined triggers. We govern definitions, targets, risk and exceptions.
Learning: When an agent fails the same way twice, we encode the fix into context documents, golden datasets, evals and gates.
What this looks like in practice
What follows is a set of explorations from the last two years. Some run in production today, while others are still teaching us where the limits are.
Loops that run end to end
Spartan is our end-to-end agentic analytics workflow, embedded across surface areas (like Slack), and most of its usage comes from people who are not analysts. On any given day, the Slack channel enables a range of analytics actions: from ads salespeople pulling spend breakdowns for a named merchant, to campaign managers sizing audiences for a target segment, and country teams asking why a number moved week on week. All of it in plain business language.
Figure 1. Index architecture across our knowledge base.
Two requests from July best demonstrate how it works. A commercial manager asked why revenue fell in the Philippines mid-market segment in the last two weeks of June. Separately, a product manager asked for a summary of a frequency-cap experiment on the ads surface. Both arrived as natural language questions in Slack and took entirely different routes through the system.
The router reads the first as a root-cause question and sends it down the diagnostic path. It identifies the best analysis framework for ads revenue, which is codified knowledge of how the metrics in that domain relate to each other, which dimensions are worth decomposing, and what counts as a meaningful move. Then it works through segment, market and campaign type against certified metrics to isolate what changed. The second question never touches the data lake. The router reads it as an experiment question, selects the experiment skill, pulls the pre-computed scorecard and the test’s own metadata from our experiment platform, and summarises the read rather than recomputing it. This is powered through 50+ skills and 120+ analysis frameworks that sit behind that routing decision. Underlying that is an index that tells the agent what to search, context that tells it how to query, and a framework that tells it how to think. Because the frameworks are shared rather than living in an analyst’s head, the interpretation compounds instead of being re-derived every time someone asks.
The second example of such a loop is Scarlet, which powers near-self-healing pipelines (L4). When a pipeline fails, an agent runs the root-cause analysis, triages, and then either fixes it or hands it to the team that owns the upstream problem. It escalates when the failure sits outside its documented runbooks or the pre-defined gates fire.
Figure 2. Scarlet in action on Slack.
Context that maintains itself
Context sets an agent’s ceiling. An agent that does not know a metric’s grain, its exclusions, and its caveats will guess and confidently produce wrong outputs at speed and at scale.
Realising the criticality of this, we have dedicated platform investment, as well as dedicated functional bandwidth to generate context docs.
Figure 3. ContextIQ.
Context goes out of date faster than anyone maintains it by hand, so we build the maintenance into our workflows. We built ContextIQ, and its Context Lifecycle Manager, to treat context as something with a lifecycle rather than a document somebody wrote once. A newer skill of ours reads an instrumentation spec alongside the existing context, proposes the SQL changes that follow from it, and updates the context document in the same pass. We work the problem from the other direction too. When we categorise an agent failure in production, we patch the context document behind it.
Two analysts recently used our internal agents to understand how the packaging fee is stored as a configuration. Having found the answer, the agent opened a merge request that committed both a certified-context table reference and a golden-dataset test case, so the next agent to ask the same question would find the answer already documented and the check already in place. One of the analysts spotted a false positive in it. The agent corrected itself and reopened the merge request. That is the learning capability working as designed, and it happened without anyone setting out to demonstrate it.
Loops that run unattended
The step from L3 to L4 is mostly the step from interactive to scheduled, and it is where we go down the path of autonomous execution, because no human is watching at the moment the work runs.
We have built root-cause analysis (RCA) as a platform capability, and it powers our automated metric and OKR commentaries, which are published through automated agents (configurable cadence). It judges whether a move is meaningful against standard deviation over six months and year on year, walks the metric tree to find which country, segment or funnel stage carried it, and correlates the operational metrics that moved alongside. Importantly, it also scans internal context for what teams changed on the ground, such as delivery fee and incentive moves, merchant visibility shifts, and experiments shipped in the same period. It also compares the movement against the same period in the previous year, which separates a seasonal effect from a real one and enables it to report a Songkran (Thai New Year) dip as amplified rather than merely expected. All of it is grounded in our own context documents, which keeps the narrative about the business rather than generic model output. The analytics owner is tagged on every report, and edits sync back so corrections land in the system.
Figure 4. OKR commentary shared through RCA agent.
Analysts as builders
The clearest evidence that our centre of gravity has moved is BriX, an internal portal we built and run ourselves.
Figure 5. Home page of BriX.
The premise is to configure once, host everywhere. We configure a system prompt, a set of context files, a model, the MCP connections and an interface once, and what comes out is a purpose-built analytics surface for a particular team or job. Each one inherits certified data, permissions and reusable agent skills rather than being wired up from scratch, and it runs wherever the work already happens: in Slack, invoked from inside an IDE, or on a schedule with nobody watching. We have grown usage more than 10x since September 2025, with strong retention, and every function at Grab now has users on it. Our aim is to put L3 workflows in the hands of people who are not advanced users.
We run it without a product manager, a technical programme manager or a designer. Our data engineers own the product, the platform, the support queue and the eval loop, with Claude Design doing the interface work and the builders triaging their own bugs. In the first half of this year, they shipped 31 production deployments, 283 merge requests and 60 features.
Three of our apps show the range:
Insights Lab is the general-purpose surface: a stakeholder asks for a metric, a breakdown or a root-cause in natural language, and the agent loads a specialist skill and answers off certified metrics rather than from memory.
We built Funnelytics to enable easy understanding of our consumer funnels. A funnel question used to mean an analyst writing the query and then assembling the view in Tableau or Power BI, and doing it again the next time someone wanted a slightly different path through the app. Now a stakeholder picks the events they care about and Funnelytics queries the raw event stream, builds the Sankey and funnel views, and writes the summary. If they cannot find the right instrumentation, which happens often on products still being redesigned, a live debugger lets them tap through the app on their own phone and watch the events fire.
Monte (like Monte Carlo) runs simulations to put a probability on a business outcome. You give each uncertain input a range rather than a single value, and it runs ten thousand scenarios to return the likelihood of hitting a target.
Figure 6. Interface of Insights Lab and Funnelytics.
Outside the portal, the same instinct shows up in smaller ways. Our analysts have been building more bespoke tools that enable better workflows for themselves and stakeholders.
The path forward
In February, 44% of the tickets our analysts closed were mechanical (data preparation, alerting, reporting); by June, that share had fallen to 30%. That capacity was redirected to other higher-leverage work, such as building new workflows to enable stakeholder self-serve, as well as more time spent on generating deeper insights for business opportunities.
Figure 7. Comparison of percentage of tickets closed in Q1 vs Q2 2026.
Importantly, our cycle times reduced by ~33%.
Figure 8. Comparison of time taken to resolve a ticket in Q1 vs Q2 2026.
The sharpest version of this sits in a Slack channel where self-serve agents are enabled. In March, an analyst had to step into half of them; by May, it was under a quarter. The share answered with no human involvement rose from 53% to 67% for metric questions, 63% to 90% for data pulls, and 50% to 81% for SQL requests. Just under three in four of the threads were started by someone outside the analytics team, and 85% of them got a first response inside a minute. Nearly every thread is logged as a ticket on the team’s board, and roughly two-thirds of the data exploration tickets on that board now arrive through the channel rather than through an analyst, and are solved by our data agents. For the ~230 tickets that arrived via the channel, if we apply a conservative assumption of 1–2 days per ticket, that is 230 to 470 business days of stakeholder asks that would have been in the backlog.
None of these arrived on a roadmap. They came from analysts who saw a loop worth automating and built it, which is why the climb is uneven. These have been strong proof points for us to believe our investments are working, and many of these workflows are starting to operate at scale. We will keep experimenting and iterating, and we expect to get a fair amount of it wrong. An analyst who owns a loop, sets its quality bar and reviews its exceptions is doing a different job from one who answers questions. Most of our team is somewhere in that transition today, and we truly believe it is changing what analytics is at Grab.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Suppose a user searches for café and your corpus contains CAFÉ, or they type straße and you’ve stored STRASSE. To make these count as matches, you need a canonical form that erases case distinctions, so that two strings which differ only in case compare equal. That form is case folding, and it shows up wherever text is matched rather than displayed: search engines, regex (?i) flags, case-insensitive usernames and hostnames.
It’s a basic operation, but at GitHub we run it a lot. Blackbird, GitHub’s code search engine, indexes over 180 million repositories—more than 480TB of source code. Every byte is case-folded before we extract ngrams and build the index, and for every potential query result, another (implicit or explicit) case folding operation is needed to locate matches. At that scale, the speed of even a basic operation starts to matter.
This post is about how we made it fast, and it starts somewhere counterintuitive: the biggest win in the ASCII fast path came from removing an optimization, not adding one. It turns out to be faster to sweep the whole buffer with no branches than to stop early at the first non-ASCII byte. We open-sourced the result as a Rust crate called casefold.
Folding is not lowercasing
It is tempting to reach for str::to_lowercase, but lowercasing and folding are different operations with different goals:
Lowercasing is for display, and it’s locale- and context-sensitive: Greek final sigma lowercases to ς at the end of a word and σ elsewhere, and Turkish I lowercases differently than English I. Case folding is for comparison, and it’s deliberately context-free and locale-independent. The point is a relation that stays stable and symmetric, so that if A folds to match B, B folds to match A in any locale. The Unicode Character Database ships an explicit CaseFolding.txt for exactly that.
The two operations diverge on real characters—ß, İ, final sigma—which is why lowercasing as a stand-in silently produces wrong matches. This crate implements only the simple (1-to-1) folds—statuses C and S in CaseFolding.txt—and not the multi-character “full” folds (ß → ss) or Turkic locale folds (the dotted İ). This isn’t an unusual choice: common tools and regex engines like ripgrep make the same restriction, and being consistent across tools is important.
The counterintuitive core: Don’t stop early
We deal mostly with source code, so the text we fold is overwhelmingly ASCII and making it run at memory speed is the single most important thing we can do. Everything else just has to keep the rare non-ASCII path from spoiling it.
The fold of an ASCII letter is trivial—A..=Z map to a..=z, everything else is unchanged—so the ASCII pass is really just “sweep the buffer, lowercase in place.” Ask any LLM for it and you might get something like this:
let bytes = s.as_bytes_mut();
for (i, b) in bytes.iter_mut().enumerate() {
    if *b >= 0x80 {
        break; // non-ASCII at index i: hand the rest to the Unicode path
    }
    if b.is_ascii_uppercase() {
        *b += 32; // 'A'..='Z' → 'a'..='z'
    }
}
It looks ideal: do the cheap byte work, and the instant you hit a non-ASCII byte, break and let the “real” Unicode path take over: “only do the cheap work until you have to.” On an Apple M4 this runs at about 3 GiB/s. That sounds fine in isolation, but it is more than 15× short of “optimal” because of the if branches.
Let’s delete every branch, line by line:
if b >= 0x80 { break } → don’t stop at all. ORevery byte into an accumulator and test it once, after the loop: high_bit_acc |= *b. Same information (was there any non-ASCII byte?), zero branches in the body.
TheA..=Zrange test → make it arithmetic. b.wrapping_sub(b'A') < 26 is true exactly for A..=Z (any other byte wraps to ≥ 26), yielding a 0/1 mask with no branch.
The conditional write → fold the mask into the store.| (is_upper << 5)sets bit 5—turning an upper-case letter lower-case and being a no-op on everything else—the byte is always written, never branched on.
What’s left has no branch in its body and no early exit:
let mut high_bit_acc: u8 = 0;
for b in &mut bytes {
    high_bit_acc |= *b; // detect any non-ASCII byte
    let is_upper = b.wrapping_sub(b'A') < 26; // branchless A..=Z test
    *b |= u8::from(is_upper) << 5; // set bit 5 → lowercase, else no-op
}
if high_bit_acc & 0x80 == 0 {
    return bytes; // pure ASCII: already folded in place, no second buffer
}
A loop with no data-dependent control flow is trivially vectorizable: LLVM emits 16-byte-at-a-time NEON and the whole thing runs at > 45 GiB/s—essentially memory bandwidth. And we come out of the pass already knowing, from high_bit_acc, whether there’s any non-ASCII work left to do.
How much did each step matter? Measuring the cumulative ladder on pure ASCII (Apple M4, 5.7 KB buffer):
Version
Throughput
Vectorized?
naive (break + branch test)
3.1 GiB/s
no (0 vector instrs)
→ branchless test/write, keep break
2.6 GiB/s
no (0 vector instrs)
→ drop the early-exit break
7.6 GiB/s
partially (25 vector instrs)
→ branchless test + write (the loop)
>45 GiB/s
fully (41 vector instrs)
The early-exit is what gates vectorization: keep the break but make the body perfectly branch-free and you still get zero vector instructions (~2.6 GiB/s); a data-dependent loop exit is enough on its own to keep the loop scalar. Only once the break is gone can the compiler vectorize. The final step—making the upper-case fold branchless—then turns a partially vectorized loop (which still compiles the conditional store to a compare-blend-masked-store, ~7.6 GiB/s) into the straight-line arithmetic that hits memory bandwidth.
Note: Branchless is apessimizationin scalar code. Look again at the table: making the body branchless while keeping the break (2.6 GiB/s) is actually slower than the naive branchy loop (3.1 GiB/s). The asm explains why. The branchy version only stores a byte when it actually changes one; its conditional strbis skipped for every lowercase letter, digit and space (the vast majority of real text), and the well-predicted branch that guards it is nearly free. The branchless version replaces that rarely taken store with an unconditionalstrbevery iteration, writing back all ~5,700 bytes instead of just the handful of upper-case ones. Extra write traffic for no benefit. Branchless-write only wins once the loop vectorizes, because then the store becomes a single 16-byte vector write regardless of content, and the per-byte cost disappears. The lesson: a branchless body is worth it only as the enabler for vectorization. On its own, in scalar code, it can cost you.
There’s also a middle ground, and it’s what standard libraries use. Instead of testing one byte at a time, [u8]::is_ascii scans a machine word at a time—on a 64-bit target it tests 16 bytes per iteration by OR-ing two u64 lanes and checking all their high bits with a single & 0x8080_8080_8080_8080 mask. You can build the ASCII fast path on top of that: chunk-scan to find the ASCII prefix, then run the branchless (vectorizable) convert over it. That keeps the early-exit ability—it still bails on the first non-ASCII block—while letting both halves go fast. The catch is that it reads the data twice (once to scan, once to convert), landing at about 23 GiB/s—roughly half of the single-pass branchless sweep, and ~7× the naive break loop. A solid, general-purpose default; just not the absolute ceiling when you control the whole loop and can fold detection and conversion into one branch-free pass.
Wouldn’tfusingthe two passes be faster? It’s the obvious next thought: keep the chunked early-exit but convert each 16-byte block right after you’ve confirmed it’s ASCII, reading the data only once. Measured, it’s ~2.6× slower—8.7 GiB/s versus the two-pass 23. The inner block convert still vectorizes to a single 16-byte op, but now there’s a data-dependent early-exit branch every 16 bytes, and that branch pins the loop to one block at a time: the compiler doesn’t unroll or software-pipeline across blocks, and each iteration pays the full load→test→branch→convert→store latency with nothing to hide it behind. Split into two passes, each one is clean: the scan is a branch-light, store-free word scan that races through memory, and the convert is the fully-vectorized branch-free sweep at >45 GiB/s. Two fast, branch-free passes beat one branchy fused pass—even though the fused version touches the data half as many times. It’s the same lesson one more time: in the hot loop, the branch is the enemy.
Avoiding the heap
Forty-Five GiB/s also means doing zero unnecessary allocation. simple_fold takes the input String by value, owning the heap buffer it can mutate and return it. If the OR-accumulator’s high bit was clear, the input was pure ASCII already folded in place. We hand the same allocation straight back, no second buffer and no copy. Otherwise, we memchrto the first non-ASCII byte and scan the tail from there, leaving the output buffer unallocated (a null write cursor) until we hit a character that folds to different bytes. Text whose multibyte content never folds—CJK, Hangul, Kana, Arabic, Hebrew, symbols—also returns the original allocation untouched, never copying a byte.
Why a second buffer rather than rewriting in place like the ASCII pass? Because folding can make the string longer: almost every fold preserves the UTF-8 length or shrinks it, but two outliers grow—U+023A (Ⱥ) and U+023E (Ɀ) are 2 bytes each yet fold to 3-byte characters (ⱥ, ɀ). Once one appears, the output no longer fits in the input’s bytes, and we need somewhere new to write.
We allocate that buffer once, sized for the worst case, rather than growing it as more folds appear. Incremental reserve calls would mean re-checking capacity, occasionally reallocating, copying everything written so far, and juggling extra length/capacity bookkeeping; a single up-front allocation lets a raw write cursor run straight to the end with none of that. And since the cursor is nulluntil that first growing/changing fold, it doubles as the “have we allocated the extra buffer yet?” flag.
Sizing it needs a bound on growth, and those same two outliers give it: every 2 input bytes yield at most 3 output bytes, capping the output at 1.5× the input—exactly the capacity we reserve:
out = Vec::with_capacity(bytes.len() + bytes.len() / 2 + 4);
After that the loop writes through a raw pointer with no capacity checks and calls set_len once at the end. Two more details keep it branch-light. The run of unchanged bytes between two folds is moved with a single copy_nonoverlapping rather than byte by byte. And each fold unconditionally writes all 4 bytes of a little-endian word before bumping the cursor by only the folded length (1–4)—dropping a branch on the output length from the hot path, with the + 4 in the reservation as the headroom that makes the final character’s over-store safe.
Making Unicode cheap too
When a character does fold, we still don’t want to fall off a cliff—decode UTF-8, hash lookup, re-encode. Unicode 16.0 has 1484 simple-fold mappings, but they’re a very sparse and very structured relation. Four observations shrink them to 1776 bytes and let the fold run without ever decoding a full character.
Even on the non-ASCII path, the overwhelming majority of characters do not fold. The hot operation isn’t really “fold this character,” it’s “does this character fold?” Almost always no. The table has to make that negative test as cheap as possible; the actual folding is the rare case on an already-rare path. That priority is what shapes the layout below—the page bitmap exists precisely so a non-folding character is rejected in a single bit test, straight from its leading UTF-8 bytes, without decoding or scanning anything.
This is exactly why a HashMap<u32, u32> is the wrong shape for the job, not just a bigger one. A hash map is optimized for the hit: it finds a present key in roughly one probe, and only spends extra work (more probes, full key comparison) when load factor or collisions bite. But our workload is dominated by misses—characters that aren’t in the table at all—and a miss is a hash map’s least favorite query: it still has to hash the key, jump to a bucket, and walk the probe sequence far enough to prove absence.
Foldable code points cluster into 64-code-point “pages”
Foldable code points bunch together. Slice the code space into 64-code-point “pages” and the ~1484 folds touch just 59 of ~1960 possible pages. A one-bit-per-page presencebitmap answers the negative test on its own: a clear bit is a definitive “no fold”—copy through, done—which is what makes fold-free scripts cheap. Only on a set bit do we consult a second structure, a cumulative-popcount side table that ranks the page (how many populated pages precede it) to find its slice of entries, storing nothing for the ~1900 empty pages.
let (word_idx, bit_idx, c_len) = if lead < 0xE0 {
    (0usize, lead & 0x1F, 2usize) // 2-byte: word 0
} else if lead < 0xF0 {
    ((lead & 0x0F) as usize, bytes[read + 1] & 0x3F, 3) // 3-byte: word = nibble

} else {
    (
        (((lead & 0x07) as usize) << 6) | (bytes[read + 1] & 0x3F) as usize,
        bytes[read + 2] & 0x3F,
        4usize,
    ) // 4-byte: merge 2 bytes
};
// reject without decoding: clear bit ⇒ no fold
if word_idx >= PAGE_BITMAP.len() || (PAGE_BITMAP[word_idx] >> bit_idx) & 1 == 0 {
    read += c_len;
    continue;
}
Because word_idxdepends only on the lead byte (and, for four-byte sequences, the first continuation byte), the bitmap load can be issued early.
Within a page, folds come in runs
A set page bit tells us something on this page folds, but not which code points or to what. The obvious encoding is one entry per foldable code point—but that is both bulky and slow to search: a page can hold dozens of folds, and we’d have to scan them all to find the one matching the current code point. The structure of the data rescues us again. Adjacent code points overwhelmingly share the same delta to their fold: A–Z all map +32, and Latin Extended is full of alternating runs like 0x0100, 0x0102, 0x0104, … where every second code point folds. Instead of per-code-point entries we store runs—start, end, stride, delta—and a 1-bit stride flag covers both the contiguous and the every-other case. This interval compression collapses the ~1484 individual folds into just 238 runs across the 59 pages (≈four per page), leaving the within-page search only a handful of entries to look at instead of dozens. This range-with-delta encoding (including the stride trick) is borrowed from Go’s unicode package, whose CaseRange records store a Lo/Hi range plus per-case deltas, with an UpperLower sentinel marking the alternating blocks. Runs are split at the page boundaries so a run never straddles two pages.
A run record is two clean bytes
With both endpoints inside one page they fit in 6 bits, split across two arrays: RUN_END_LOW[``i``] = end & 0x3F (the scan key) and RUN_START_STRIDE[``i``] = (start & 0x3F) | ((stride − 1) << 6) (read only on a hit). Because each key is one clean byte, the within-page search can go wide: rather than comparing cp & 0x3F against the runs one at a time, we load 8 end_low bytes into a single u64 and test all of them at once with one branchless SWAR step—(chunk | 0x80…80) − broadcast(low) & 0x80…80 sets the top bit of every lane whose key is ≥ cp & 0x3F. A single bit-scan of that mask (the keys are sorted, so the first set lane is the run we want) finds the slot. A page holds ~4 runs on average; that one 8-wide compare almost always resolves the entire search in a single step. One unlucky page does hold 30 runs, which puts the compare inside a short loop that strides eight keys at a time—but that loop trips at most a handful of times on exactly one page in all of Unicode, and never on the common ones. Either way: no per-run branch, and no code-point reconstruction anywhere.
/// Offset of the first run with `end_low >= low_v` in a page of `n` runs,
/// or `n` if none. Scans 8 `end_low` bytes at a time via SWAR.
#[inline]
fn scan_end_low(lo: usize, n: usize, low_v: u8) -> usize {
    const HIGH: u64 = 0x8080_8080_8080_8080;
    const ONES: u64 = 0x0101_0101_0101_0101;
    let bcast = (low_v as u64).wrapping_mul(ONES);
    let mut base = 0;
    while base < n {
        // RUN_END_LOW is padded by 8 bytes so this read is always in bounds.
        let chunk = u64::from_le_bytes(
            RUN_END_LOW[lo + base..lo + base + 8]
                .try_into()
                .expect("8-byte slice"),
        );
        // `(b | 0x80) - low_v` keeps its high bit iff `b >= low_v` (no
        // cross-lane borrow). The first set lane is the first run `>= low_v`.
        let ge = (chunk | HIGH).wrapping_sub(bcast) & HIGH;
        if ge != 0 {
            let j = base + (ge.trailing_zeros() / 8) as usize;
            return if j < n { j } else { n };
        }
        base += 8;
    }
    n
}
Folding is a little-endian byte addition
On a little-endian machine the folded character’s UTF-8 bytes, read as a u32, equal the source bytes (as a u32) plus a per-run constant. A parallel BYTE_DELTA[i] table then turns the whole fold into a masked load, one wrapping_add, and a 4-byte store:
let word = u32::from_le_bytes(next_four_bytes) & length_mask; // keep this char's bytes
let folded = word.wrapping_add(BYTE_DELTA[i]); // the fold, as one byte add
write_u32_le(dst, folded); // store all 4 bytes...
dst += utf8_len(folded); // ...advance by the folded length
Both lengths in that snippet—the length_mask for the source character and the advance by the folded length for the destination—come from one more tiny trick. A UTF-8 sequence’s length is fixed by the top four bits of its lead byte, letting the 16 possible lengths pack one nibble each into a single 64-bit constant (0x4322_1111_1111_1111); the length is then a shift and a mask, (LEN_BITS >> (4 * (lead >> 4))) & 0xF—no if chain, no table memory, nothing for the predictor to get wrong. (A count leading ones—(!lead).leading_zeros()—would also work, since a lead byte carries one leading 1-bit per byte of the sequence.)
/// Number of bytes in the UTF-8 sequence whose lead byte is `lead`.
#[inline]
pub fn utf8_len(lead: u8) -> usize {
    const UTF8_LEN_BY_LEAD: u64 = 0x4322_1111_1111_1111;
    ((UTF8_LEN_BY_LEAD >> (4 * (lead >> 4))) & 0xF) as usize
}
Because we advance by the folded length, this even handles length-changing folds—U+212A KELVIN SIGN (3 bytes) → k (1 byte), or U+023A Ⱥ (2 bytes) → U+2C65 ⱥ (3 bytes)—by writing fewer or more bytes than were read. That’s the part we believe is genuinely new: every other folder we looked at—ICU, Go’s unicode, Rust’s regex, CPython, glibc—decodes UTF-8 to a code point, applies the fold there, and re-encodes (even SIMD folders decode first). Doing the arithmetic in byte space skips both the decode and the encode, which is exactly why this path can outrun a hash map that already has the answer tabulated—the hash map still has to decode its key and encode its result. The byte-space arithmetic assumes the input is well-formed, shortest-form UTF-8—every code point encoded with the minimal number of bytes. Reading the source bytes as a u32and adding a per-run delta only lands on the correct folded encoding when the source is in canonical form; an overlong encoding (a code point padded into more bytes than necessary, e.g. / as 0xC0 0xAF) has a different byte pattern and would break thelength_mask and the delta arithmetic. This is not a real restriction in Rust—&str/String are guaranteed to hold valid UTF-8, which by definition rejects overlong sequences—but a caller feeding raw bytes from elsewhere must validate (or otherwise normalize) them first.
The ASCII shortcut in the tail loop
One more shortcut rounds out the tail loop. Remember the first pass already lowercased every ASCII byte, so when the scan meets an ASCII byte in the tail it advances a single byte and moves on—no page probe, no table touch at all. And it doesn’t copy that byte either: unmodified bytes (ASCII and non-folding multibyte alike) aren’t moved one at a time. The scan just keeps walking until it reaches a character that actually folds, then flushes the whole unchanged run between the last fold and this one with a single copy_nonoverlapping. Mixed text—CJK with ASCII spaces and punctuation, or code with the occasional accented identifier—therefore races through the ASCII filler and only consults the bitmap for genuine multibyte characters, copying in bulk rather than byte by byte.
Putting it together: the whole table
Component
Bytes
PAGE_BITMAP (1 bit per 64-cp page)
248
POPCNT_SAMPLES (cumulative popcount)
32
PAGE_OFFSET (per populated page)
60
RUN_END_LOW (scan key, end & 0x3F, +8 pad)
246
RUN_START_STRIDE (start & 0x3F | stride)
238
BYTE_DELTA (little-endian fold delta per run)
952
Total
1776
That’s 9.6 bits per fold entry, over half of it the BYTE_DELTA side table we trade for the decode-free path; the index + run records alone are ~4.4 bits/entry.
Next to the obvious alternatives, that 1776 bytes is an order of magnitude or more smaller—and unlike most of them, it never decodes a character:
Representation
Size
Naïve [(u32, u32); 1484]
~11.6 KB
regex-syntax’s case_folding_simple table
~70 KB
Go’s unicode.SimpleFold (orbit + ASCII + ranges)
~7.3 KB
A runtime HashMap<u32, u32>
~17 KB
This crate (paged bitmap + packed runs)
1776 B
Where it lands against the alternatives
On the common case, ASCII, folding runs at memory bandwidth (>45 GiB/s), more than an order of magnitude ahead of other real folders and more than 50% faster than the (non-equivalent) str::to_lowercase function. To get a rough “upper bound” for the non-ASCII case, we measured the optimized Utf8 decoding + encoding round trip without performing any actual case folding using the simdutf crate. This experiment achieves consistently about 2GB/sec and is only about twice as fast than our solution for the worst case all-folding input. A naive hash map trails everything on all workloads.
The three columns are real case folders that produce identical output: simple_fold (this crate), simd_normalizer (the simd-normalizer crate), and HashMap (naive CaseFolding.txt lookup). The workload rows are chosen to simulate different scenarios from typical to worst case:
Workload (input size)
simple_fold
simd_normalizer
HashMap (byte path)
Pure ASCII (5.7 KB)
>45 GiB/s
1.21 GiB/s
213 MiB/s
Chinese/Japanese/Korean, no folds (8.1 KB)
2.95 GiB/s
1.97 GiB/s
558 MiB/s
Symbols / Myanmar, no folds (9.0 KB)
2.96 GiB/s
1.56 GiB/s
410 MiB/s
Worst case: Latin/Greek/Cyrillic (Unicode U+0000–U+FFFF), all folding (8.8 KB)
869 MiB/s
922 MiB/s
334 MiB/s
Length-changing folds (1.7 KB)
1.26 GiB/s
716 MiB/s
233 MiB/s
Treat the absolute figures as illustrative, not portable: the whole design leans on auto-vectorization, SWAR, and little-endian byte arithmetic, so the numbers—and even the ratios between rows—can shift substantially on a different microarchitecture (a wider or narrower vector unit, different memory bandwidth, a big-endian target, x86 vs ARM).
Case folding is about as basic as text operations get, which is exactly why it was worth the effort: we run it across every byte we index. The wins came from two ideas that both cut against instinct—sweep the whole buffer branch-free instead of stopping early, and do the fold as byte-space arithmetic instead of decoding to a code point. Together they let the common case run at memory bandwidth and the rare fold run without a decode, in a table small enough (1776 bytes) to stay resident. The decode-free byte-space fold is the piece we believe is genuinely new; it’s why this path can beat a hash map that already has the answer.
There’s surely more to find here, and we’d like to see it. The crate is casefold; the generated table and full design notes live alongside the source.
The efficacy of semantic search relies on the accuracy of the underlying Knowledge Graph (KG). In high-velocity domains like on-demand food delivery or e-commerce, the catalog of entities like dishes, products, and merchants changes rapidly.
Current methods for KG construction and maintenance face three critical challenges:
Inaccuracy and hallucination from Large Language Models (LLMs): Automated models often infer relationships based on statistical text co-occurrence rather than semantic reality. For instance, an LLM might incorrectly classify “Pho” as a child of “Italian Noodle Soup” due to linguistic similarity, leading to irrelevant search results.
Scalability limits of manual verification: Traditional verification relies on human annotators or domain experts. This approach is slow, expensive, and unable to keep pace with dynamic catalogs containing millions of entities. For example, daily changes in restaurant menus or grocery stock keeping units (SKUs).
Error propagation in ranking: Inaccurate graph edges propagate errors downstream. If a parent-child relationship is wrong, query expansion algorithms will retrieve irrelevant items, directly degrading Click-Through Rate (CTR) and user trust.
We introduce a feedback-driven verification engine that operationalizes the search interface as a validation environment. Key contributions include:
User feedback-driven verification: The system treats unverified graph edges as hypotheses. Instead of accepting them as truth, it tests them against live traffic by injecting them into search suggestions and measuring user engagement.
Hierarchical relationship refinement: Unlike systems that only validate entities (nodes), this framework validates structural links (edges). It confirms whether entity A is truly a parent, child, or sibling of entity B, ensuring structural integrity.
Adaptive exploration: The system employs a greedy exploration policy. It intelligently balances exploitation by showing known good results with exploration through injecting unverified candidates to gather data without degrading the user experience.
Background
Automated KG construction using LLMs and unstructured content extraction can scale quickly across large, dynamic catalogs. However, relationships inferred from text co-occurrence or vector similarity do not always reflect semantic reality. Manual verification by domain experts remains accurate but does not scale to millions of entities that change daily.
When inaccurate edges enter the graph, ranking and query expansion systems propagate those errors to users. Incorrect parent-child or sibling links lead to irrelevant search results, reduced CTR, and lower user trust. An additional solution is required that can validate graph structure continuously, at scale, without relying solely on manual curation.
Solution
The overall workflow of this invention is shown in the following figure. The details of each step are explained in this section.
Figure 1. The system architecture.
The proposed framework functions as a closed-loop validation ecosystem. It is composed of four integrated modules designed to continuously cycle data from the KG to the user interface and back, using real-world interactions to separate semantic truth from artificial intelligence (AI) hallucinations.
The verification process follows a continuous, iterative loop that cycles data from the backend graph to the frontend user interface and back. This four-step procedure operationalizes the human-in-the-loop validation mechanism:
Hypothesis generation
Candidate injection
Signal aggregation and scoring
Graph update logic
Architecture details
KG core
The central repository acts as the source of truth, storing entities such as dishes, products, or merchants, and the connections between them. To manage the verification process, the system introduces a specialized metadata layer that classifies every connection (or edge) into one of two distinct states:
Verified edges: These are established relationships that have been validated either by high historical traffic or human confirmation. They represent the safe structure of the graph. For example, “Sushi” is definitely a child of “Japanese Cuisine”, and is used to power standard search results.
Candidate edges: These are probabilistic, unverified relationships generated by automated LLMs or content scrapers. They are treated as hypotheses waiting to be proven. For example, if an LLM ingests a blog post and predicts that “Pho” is related to “Italian Noodle Soup,” this link is stored as a candidate edge, invisible to the main search algorithm until validated.
Search and injection module
This module sits between the KG and the user, intercepting the query execution pipeline. Unlike standard ranking algorithms, which strictly optimize for relevance by showing only the best results, the injection engine employs a balanced strategy known as exploration vs. exploitation.
The injection mechanism: When a user performs a search, the system retrieves a list of high-confidence results (exploitation). Simultaneously, it deliberately retrieves a small subset of candidate edges related to the query. It injects these unverified candidates into specific, lower-risk slots within the user interface, such as the third or fourth position in a related searches chip carousel.
Risk management: To prevent user frustration, the system limits the number of candidates shown per session. This ensures that the user is primarily served helpful, verified content, while still providing enough data points to test new hypotheses.
Behavior tracking module
To accurately measure whether a candidate relationship is valid, the system tracks user micro-interactions with high granularity. It captures not just the final click, but the precise context in which the interaction occurred to determine semantic intent.
Contextual anchoring: The system logs the specific search term, also known as the anchor, used by the user. A click on “Pho” is only counted as a vote for the relationship if the user was searching for “Noodle Soup” at the time.
Signal classification: Signals are assessed in aggregate to estimate the relevance of a candidate relationship. Higher-intent engagement contributes stronger positive evidence, lighter exploratory behavior contributes weaker positive evidence, and lack of engagement or explicit negative actions contributes negative evidence.
Verification and refinement engine
This is an offline processing unit that acts as the final judge. It aggregates thousands of individual user signals to update the topology of the KG.
Relevance scoring: Instead of complex formulas, the engine calculates a simple confidence ratio. It looks at the total number of times a candidate was shown versus the number of positive interactions it received.
Graph topology updates:
Promotion (verify): If the confidence ratio exceeds a verification threshold. For example, if the candidate performs as well as known good items, the edge is upgraded from candidate to verified. It becomes a permanent part of the graph and is shown to all users.
Demotion (prune): If the candidate consistently fails to garner engagement or receives negative signals, it falls below a pruning threshold. The system automatically deletes this edge, effectively correcting the AI’s hallucination and cleaning the dataset.
Implementation
Hypothesis generation
The process begins by identifying a target subject, referred to as the anchor entity. For example, the specific dish “Pho”. The system queries the KG to retrieve a set of potential relationships. This retrieval includes both verified neighbors, where relationships are already confirmed by experts, and candidate neighbors, where the relationships are predicted by AI models but not yet proven.
Candidate injection
Once a hypothesis is selected, the system exposes it to real users to gather evidence. When a user actively searches for the anchor entity, the system dynamically injects the candidate neighbor into the search results.
User interface (UI) implementation: The candidate is presented alongside verified items, typically in a related categories carousel or a refine search chip list. This reflects standard relevance experimentation in search, with safeguards to ensure the experience remains controlled and measurable.
Exposure logging: The system logs an impression event specifically linking the anchor to the candidate. This record serves as the baseline, documenting that the user saw the relationship, which is essential for calculating future engagement rates.
Signal aggregation and scoring
Instead of using a raw count of clicks, the system calculates a sophisticated relationship confidence score by aggregating user interactions over time. This scoring model uses a weighted tier system to distinguish between casual interest and strong intent.
Weighted interaction logic: The system assigns a higher value to actions that require more effort or commitment. For example, a “Purchase” or “Add-to-Cart” action is weighted significantly heavier than a simple click, as it indicates a strong validation of the relationship. Conversely, scrolling past the item quickly or skipping is treated as a negative signal.
Normalization: To ensure fairness, the total weighted score is normalized against the total number of times the candidate was shown. This prevents niche items with low total traffic but high accuracy from being unfairly penalized.
Graph update logic
Periodically, the verification engine evaluates the confidence score against predefined benchmarks to update the KG’s topology. This is a binary decision process:
Validation (cementing the edge): If the accumulated confidence score exceeds a strict validation threshold, the system concludes that the relationship is genuine. The status of the edge is updated from candidate to verified. This permanently adds the relationship to the graph, ensuring it appears in future standard searches without the need for further testing.
Rejection (pruning the edge): Conversely, if the score falls below a rejection threshold, indicating that users consistently ignore or reject the suggestion, the system concludes the relationship is an AI hallucination. The edge is severed or removed from the graph. This pruning action cleans the dataset, preventing the system from making the same bad recommendation again.
Case study: hierarchical refinement in food delivery
To demonstrate the framework, consider a validation scenario in food delivery taxonomy. An LLM-based ingestion pipeline flags a candidate parent-child link Noodle Soup → Dry Mee Pok and stores it as an unverified candidate edge in the KG, ready for live validation.
User-triggered validation:
When a user searches for “Noodle Soup,” the search module injects the candidate alongside verified results. For example, in a “Refine by Dish” filter carousel, and logs an impression linking the anchor query to the candidate.
Outcome collection:
User interactions like clicks, dwell time, scroll behavior, and conversions are captured and weighted over the validation window. The verification engine aggregates these signals and updates the graph: relationships that meet the validation threshold are promoted to verified status; those that fail are pruned or re-mapped to a more appropriate parent node.
Impact
By injecting unverified candidate edges into live search results and recommendation interfaces via a multi-armed bandit (MAB) exploration strategy, the system leverages implicit user feedback to validate semantic truth. This dynamic, human-in-the-loop mechanism effectively prunes erroneous connections and reinforces accurate taxonomies without the need for manual curation, significantly enhancing search relevance in dynamic domains such as food delivery and retail.
The case study demonstrates how the framework validates candidate relationships through live user traffic, collecting interaction signals and updating the graph without manual curation.
Learnings and conclusion
The feedback-driven verification engine operationalizes the search interface as a validation environment for KG relationships. By classifying edges as verified or candidate, injecting candidates through an exploration vs. exploitation strategy, and aggregating weighted user signals, the system promotes accurate relationships and prunes AI hallucinations at scale.
Unlike approaches that validate only entities, this framework validates structural links, confirming whether entity A is truly a parent, child, or sibling of entity B. The food delivery case study shows how a user-triggered search can initiate validation and outcome collection at scale, without manual intervention.
What’s next
Hierarchical confidence tiers
To safely graduate new connections into the production graph, we are introducing a dual-measurement trust system that requires both volume and variety before a new connection goes live: support mass (product hits, graph depth, recency) and corroboration (unique sessions, anonymous cohorts, and temporal spread). Connections must climb a strict state machine: proposed → shadow eligible → canary eligible → production, advancing only when both metrics meet progressively higher thresholds; if a snapshot causes metrics to fall below a tier’s floor, the connection is automatically demoted.
Adversarial and spam resistance
To prevent bad actors, bots, or highly repetitive users from manipulating the search graph, we are building a multi-layered defense system. We enforce per-merchant rate limits and anti‑abuse controls: hourly caps per session/device, exponential backoff for rapidly repeated actions, and a short (few‑hour) freeze of promotions from any user cohort after declines or “irrelevant” signals. For bot and Sybil attack defense, traffic flagged by abuse systems is excluded from trust calculations (but logged for analysis); votes must come from diverse network subnets or cohort buckets, and each bucket is subject to a daily contribution cap.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
If you maintain an active repository, you know the feeling. You open your notifications on a Monday morning and there they are: five, 10, sometimes a dozen Dependabot pull requests, each bumping a single dependency by a single patch version. Individually, every one of them is helpful. Collectively, they’re noise. And noise is how important updates get ignored.
We looked at Microsoft’s GCToolkit, an open source Java library for analyzing garbage collection logs. As of July 2026, a git log of the repository showed that 92 of its 578 commits, roughly one in six, were Dependabot version bumps, with 61 in the previous 12 months alone, sometimes several in a single day. That’s a lot of review, merge, and CI cycles spent on routine maintenance.
The good news: Dependabot already ships with the features to fix this. In a recent pull request, the project changed its dependabot.yml in three small but meaningful ways, turning a daily drip of single-dependency pull requests into a predictable, grouped, monthly batch per ecosystem. Here’s what changed, why it works, and how to apply the same pattern to your own repositories, following the GCToolkit example.
The problem: Good defaults, wrong cadence
Here’s what GCToolkit’s configuration looked like before:
This is a common starting point, but the daily interval here was a deliberate choice, not a default: schedule.interval is required, and GitHub’s suggested starter template uses weekly. Two things make this configuration noisy:
interval: daily tells Dependabot to check for updates every weekday (Monday through Friday). For a repository that references a handful of GitHub Actions, that can mean new pull requests landing on any weekday.
No grouping means every dependency gets its own pull request. Ten available updates equals 10 pull requests, 10 CI runs, and 10 review notifications.
The open-pull-requests-limit: 10 line is a symptom, not a cure: it caps the flood at 10 open pull requests, but it doesn’t stop the flood.
Three things are happening here, and they build on each other.
1. Group everything into a single pull request
The groups block is the heart of this change:
groups:
  monthly-batch:
    patterns:
      - "*"
A Dependabot group bundles multiple dependency updates into one pull request. The name (monthly-batch) is yours to choose. It shows up in the pull request title and branch name. The patterns list decides which dependencies belong to the group, and "*" is a wildcard that matches all of them.
So instead of 10 pull requests, you get one pull request titled something like “Bump the monthly-batch group with 10 updates.” One branch. One CI run. One review. If the whole batch is green, you merge once and you’re done. If something breaks, it’s contained in a single, reviewable place.
For larger projects, you don’t have to lump everything together. You can define multiple named groups with more specific patterns. For example, you could keep all your testing libraries in one group and your production dependencies in another, so related updates travel together and unrelated ones stay separate.
Grouping keeps getting more capable, too. In a February 2026 update, Dependabot gained the ability to group updates for the same dependency across multiple directories into a single pull request. That’s aimed squarely at monorepos: if one library is pinned in a dozen services, a single bump used to open a dozen near-identical pull requests, one per directory. Now you can point the directories key (note the plural) at a list of paths, or a glob like /apps/*, and let your group collapse all of them into one:
That’s the same monthly-batch group as before, now spanning every service in the repository instead of a single directory. For the full set of options, see the Dependabot options reference.
2. Slow the cadence from daily to monthly
schedule:
  interval: "monthly"
Switching from daily to monthly changes the rhythm from “whenever anything changes” to “once, on a schedule you can plan around.” Combined with grouping, this is the real noise reduction: Dependabot now opens one batched pull request per ecosystem, per month, instead of a steady trickle all month long.
Monthly is the right call for a mature library where dependencies are stable and updates are rarely urgent. If you want something in between, weekly is also available, and you can pin the exact day and time with schedule.day and schedule.time.
3. Cover every ecosystem you actually use
The original config only requested version updates for github-actions. But GCToolkit is a Java project built with Maven, so its application dependencies weren’t receiving Dependabot version updates. The updated config adds a second updates entry:
- package-ecosystem: "maven"
  directory: "/"
This is an easy one to miss. Reducing noise is only half the win; the other half is making sure Dependabot is watching the dependencies that matter most. Each ecosystem gets its own schedule and its own group, so your Actions updates and your Maven updates arrive as two clean, separate batches.
But what about security updates?
This is the question every maintainer should ask before slowing anything down, and it’s where the design really shines: by default, the groups and schedule you set here shape your version updates, not your security fixes.
Dependabot security updates are raised as soon as a vulnerability with a fix is disclosed, independent of your schedule and separate from your version-update groups. So a monthly batch cadence for routine bumps doesn’t delay a critical patch. (You can batch security fixes on purpose with a group scoped to applies-to: security-updates, but even then they’re triggered by disclosures, not by your version-update schedule.)
One caveat: this safety net only exists if Dependabot security updates are actually turned on for the repository, which also requires the dependency graph and Dependabot alerts to be enabled. Confirm those are on before you rely on a slower version-update cadence. Do that, and you get the best of both worlds: quiet, predictable maintenance for the routine stuff, and immediate action when a real vulnerability lands.
That separation is what makes “slow down Dependabot” a safe recommendation rather than a risky one.
A new safety net: default package cooldown
There’s one more piece of noise reduction that landed recently, and it happens automatically. Dependabot now waits until a new release has been on its registry for at least three days before opening a version-update pull request. This cooldown is the default and requires no configuration.
Why wait? A brand-new release is one of the most common entry points for a supply chain attack. A compromised or simply broken version can reach your dependency updates before maintainers and the wider community have caught the problem. A short delay gives that signal time to surface, so you’re far less likely to merge a bad release the moment it ships.
Two things worth knowing:
It only applies to version updates. Security updates still open immediately, so critical fixes are never held back by the cooldown.
You stay in control. Use the cooldown option in your .github/dependabot.yml to widen or shorten the window, tune it per semantic-versioning level, or opt out entirely:
Pair cooldown with grouping and a monthly cadence and the effect compounds: fewer pull requests, and the ones you do get have had a few days to prove they’re safe to merge.
How to apply this to your own repositories
You can adopt this pattern in a few minutes:
Open (or create) .github/dependabot.yml in the default branch of your repository.
For each package-ecosystem you depend on, set schedule.interval to weekly or monthly.
Add a groups block with a single wildcard group (patterns: ["*"]) to batch updates into one pull request per ecosystem.
Make sure every ecosystem you actually ship with is listed: not just github-actions, but maven, npm, pip, gomod, docker, and so on.
Commit, and let the next scheduled run produce a single, grouped pull request.
A few tips as you tune it:
Start broad, then split. A single wildcard group is the simplest starting point. If you later find you want, say, patch-level and major-version updates handled differently, break the wildcard into more targeted named groups.
Don’t fold security fixes into this cadence. Dependabot security updates are triggered by vulnerability disclosures, not your version-update schedule, so a monthly cadence never delays them. You can even group them with applies-to: security-updates without slowing them down.
Lean on cooldown. The three-day default already shields you from brand-new bad releases; bump cooldown.default-days higher if you want an even wider safety margin on version updates.
Right-size the interval. Fast-moving apps may prefer weekly; stable libraries do fine on monthly.
Consolidate monorepo directories. If the same dependency lives in many directories, list them under directories and set group-by: dependency-name in the group so a single bump produces one pull request instead of one per directory.
The takeaway
Dependency updates are one of those chores that’s easy to automate and then easy to start ignoring, which defeats the purpose. The fix isn’t to turn Dependabot off or to merge pull requests without looking. It’s to shape its output so that the routine work is quiet and batched, and the urgent work still cuts through.
GCToolkit did it with about a dozen lines of YAML: group everything, slow the cadence to monthly, and make sure every ecosystem is covered. Add the new default cooldown on top, and even that monthly batch has had a few days to prove itself before it reaches you. The result is fewer pull requests, fewer CI runs, and, most importantly, a review queue where the updates that matter don’t get lost in the ones that don’t.
Further reading: once the routine pull request noise is under control, the harder question is which security alerts to fix first. Our earlier post, Cutting through the noise: How to prioritize Dependabot alerts, walks through using EPSS scores and repository properties to turn an overwhelming alert list into a clear, risk-ranked queue.
At Grab, AI agents have evolved from interesting team prototypes into production services used every day by millions of merchants, drivers, and consumers. Today, more than 500 services run on our internal agent framework, over 50 Model Context Protocol (MCP) servers are registered on our remote MCP framework, and a single Large Language Model (LLM) gateway fronts every model call across the company, handling billions of tokens each month.
None of this was designed up front. It began as the plumbing behind one internal support bot, which then expanded because the same problems kept resurfacing for every team trying to ship an agent. This series tells the story of what the platform eventually became. This Part 1 of the blog focuses on the beginning: the architecture of our AI support bot, the specific pain points we hit while scaling and iterating on it, and how each of those failures became a core building block in the framework we now call LLM-Kit.
The bot that started it
Imagine you have a question for the Technical Infrastructure (Tech Infra) team – the engineers who run the cloud platforms, databases, developer tooling, and AI infrastructure behind Grab’s ecosystem. Instead of immediately paging an on-call engineer, a bot first triages the request, checks the team’s documentation, runbooks, and past Slack threads, and tries to answer directly in the thread. If it still cannot resolve the issue, it routes the ticket to the right human, with the relevant context already attached.
That is what we built with the Tech Infra Support Bot.
In the first half of 2023, Tech Infra handled thousands of support tickets, many of them repeated questions that had already been answered somewhere internally. Before LLMs, the bot’s role was mainly operational; performing tasks like helping track acknowledgments and response times for on-call engineers. With the arrival of GPT-4-32k, we evolved it into a GPT-powered Level-0 support layer that could answer documented questions before a human needed to be paged.
The first production version was a Go service organized around two planes:
A reasoning plane. At Level-0, it was a single-agent loop. It takes the user’s question, decides which tools to call, executes those calls, feeds the results back into the prompt, and returns an answer. The default model at the time was gpt-4.1; today, we have evolved to the latest reasoning models.
A tool plane. The tools provided the bot’s core working context. Retrieval flowed through Glean, which covered Confluence, TechDocs, internal drives, and Jira. Other tools handled log search through Kibana, GitLab runbook and file access, Slack conversation search, and a small set of Hypertext Transfer Protocol (HTTP) plugins. In the first version, tools and prompts were defined in per-channel JavaScript Object Notation (JSON) configs and resolved at request time. As models became more capable, we later standardized the tool set across channels.
A trimmed version of that tool config looked like this:
It worked, but it taught us, the hard way, why a demo agent is not a production agent.
What it takes to scale and improve quickly
As we worked on improving the agent, we kept running into the same kinds of friction. Over time, those pain points formed clear patterns, and they were the same ones we saw other teams run into as well.
Vibe check is not an evaluation strategy. The bot had a base prompt, and each Slack channel could configure its own prompt, tools, and documentation filters. But the workflow was essentially: configure it, ship it, and hope it reduced toil. There were no real evaluations, just optimism that it would work.
Fast model and provider switching is essential. The AI landscape moves incredibly fast: a new state-of-the-art (SOTA) model appears on Tuesday, and a highly efficient open-source alternative shows up on Thursday. Switching providers should not feel like open-heart surgery. A unified Software Development Kit (SDK) and an LLM API gateway remove the need to refactor payload schemas, rewrite error handling, or integrate each provider from scratch. If moving from OpenAI to Anthropic, or routing to an open-source model endpoint, takes more than a few config changes, technical debt is already slowing you down.
Observability cannot be an afterthought. When an answer was wrong, figuring out “why” meant grepping logs across three separate systems: the agent workflow, the tool calls, and the model call. There was no shared trace tying them together. That level of friction is survivable for an internal tool; it is unacceptable for a customer-facing agent.
Everything around the agent took longer than the agent itself. Auth (OIDC), secrets management (Vault), per-environment config, vector database integration, LLM tracing, health probes, and metrics were not agent-specific problems. However, they all had to be solved before anything could be shipped. The reasoning loop took a whole afternoon. The production wrapper took two weeks.
The pattern was clear: the hard part of building an agent was not the agent itself, but everything around it that had to be in place before it could safely run in front of users. So we began pulling those shared components out of the bot and consolidating them into a unified framework.
Extracting the framework: LLM-Kit
LLM-Kit emerged when we stopped solving these problems service by service and started solving them once, centrally. It is intentionally not a new agent abstraction or a Domain-Specific Language (DSL). Instead, it is a curated set of integrations and scaffolding built around Grab’s existing infrastructure, pipelines, secret management, and observability. Just as importantly, we chose to build a framework rather than a heavy centralized platform. In a space evolving this quickly, a platform would have locked teams into rigid assumptions that would soon become outdated. A framework let us meet developers where they already were: standardizing the plumbing while preserving the freedom to iterate quickly. Looking back, that was the right first choice. Each part of LLM-Kit is a direct response to one of the failures described above.
We first wrote about LLM-Kit’s structure and code architecture in a 2024 blog post. Two years and a few hundred agents later, the overall shape is still recognizable, but almost every underlying layer has changed. Poetry was replaced by uv; we standardized on the OpenTelemetry stack; LangChain evolved into LangGraph and Deep Agents; and some tools moved onto our MCP framework.
It starts with a template. The entry point is a user interface (UI) form. An engineer fills in an application name and a few details, and gets back a GitLab repository with the production wrapper already assembled. Under the hood the template stamps out a full FastAPI service:
/
├── app/
│   ├── server.py              # FastAPI app factory: mounts routes + middleware, boots OTel + statsd
│   ├── agents/
│   │   ├── simple_react_agent.py   # a single-agent LangGraph ReAct loop (agent <-> tools)
│   │   ├── mcp_react_agent.py      # the same loop, but tools are pulled from remote MCP servers
│   │   └── simple_react_agent.png  # auto-exported graph diagram (generated in dev)
│   ├── routes/
│   │   ├── api.py             # router aggregator
│   │   ├── health_check.py    # liveness/readiness probe
│   │   ├── oidc.py            # OIDC login/callback (skipped in proxy-auth mode)
│   │   └── evalshub_eval.py   # runs ROUGE / BLEU / LLM-as-judge evals on the agent
│   ├── core/config.py         # AppConfig (pydantic-settings) + INI/secret parsing
│   ├── tools/word_length_tool.py   # an example tool to copy from
│   ├── utils/prompts.py       # prompt/message assembly helpers
│   └── storage/connection.py  # Postgres + pgvector engine and connection pooling
├── sdk/         # a generated, typed client SDK (protobuf) other services import
├── configs/
│   ├── dev.ini / stg.ini / prd.ini   # one config per environment
│   └── secret.ini.example     # secret template; real values resolve from Vault at deploy
├── databases/postgresql/      # SQL migrations (pgvector extension bootstrapped for you)
├── scripts/
│   ├── db.py / db.sh          # migration runner
│   └── gunicorn_conf.py       # production server/worker config
├── tests/
│   ├── unit_tests/            # starter unit tests (e.g. the health check)
│   └── evalshub_evaluation/   # golden test cases the eval route runs against
├── Dockerfile                 # multi-stage, distroless
├── Makefile                   # setup / run / test / lint targets
├── pyproject.toml             # uv build backend + pinned deps
└── .pre-commit-config.yaml
Three things are worth pulling out of that tree:
app/agents/ is the part you actually own. You get two working agents to fork from rather than a blank file: simple_react_agent.py is a single-agent LangGraph ReAct loop, and mcp_react_agent.py is the same loop wired to pull its tools from remote MCP servers. Both compile to a LangGraph StateGraph with a retry policy and a 30-second per-step timeout, and in dev the graph is auto-exported as a diagram. This is a real step up from the bare LangChain agent initialization we scaffolded in 2024.
app/routes/evalshub_eval.py ships evals on day one. The template comes with an endpoint that runs Recall-Oriented Understudy for Gisting Evaluation (ROUGE), Bilingual Evaluation Understudy (BLEU), and LLM-as-judge evaluators over a set of golden test cases in tests/evalshub_evaluation/. The thing we most wished the support bot had, is now in the box before a builder writes a line of their own logic.
Everything else is the production wrapper. core/config.py, storage/, configs/, databases/, scripts/, the distroless Dockerfile, and the pyproject.toml (now uv, not the Poetry we used in 2024) are the auth, secrets, persistence, packaging, and deploy plumbing that every service needs and that no team should have to write from scratch.
The day-one wiring that used to take two weeks or more now takes about an hour. The rest of this section is what “pre-wired” means, layer by layer.
Config and secrets are solved once. Apps declare environment configs as initialization (INI) files with secret interpolation, so secrets resolve from Vault at boot, and a single secret.ini.example is enough to run any LLM-Kit app locally:
Model access behind one resolver. Every model call goes through the GrabGPT Gateway, which is OpenAI-compatible. LLM-Kit’s job is just to resolve the right endpoint (per environment, and per data tier) and inject the key so application code never hard-codes a provider again:
That one indirection is what later lets a platform team change which provider serves a model, configure fallback routing, set budgets, and manage cost attribution, without a single application touching its code.
Tracing wired in, not bolted on. A single instrumentor auto-instruments FastAPI, outbound HTTP, LangChain, and MCP, and stamps every span with Kubernetes resource attributes (pod, namespace, image, service version). Structured logs auto-inject the trace and span IDs, so logs and traces correlate in Grafana/Kibana for free:
The three systems, no shared trace problem turns into one end-to-end trace across every LLM call, tool call, and retrieval step.
Tools can be exposed through MCP servers built on our MCP framework. Instead of hardwiring a large set of tool functions inside the agent process, the agent connects to MCP servers and discovers their tools at runtime. That means adding a new capability can be as simple as registering an MCP server, rather than redeploying the agent.
client=MultiServerMCPClient({"mcp-gitlab-remote":{"transport":"streamable_http","url":"<remote-mcp-gitlab-endpoint>/mcp/","headers":{"Authorization":"Bearer <token>"},}})tools=awaitclient.get_tools()# schema negotiated, no redeploy
An agent is just another service in the ecosystem, with gRPC on both sides. Most of Grab’s backend communicates over gRPC, and agents are rarely standalone; other services call them, and they in turn call other internal services. The template is designed to support both directions.
On the serving side, the scaffold includes a Protocol Buffers (protobuf) contract (sdk/.../.proto, with a sample Hello remote procedure call (RPC)) and a generated, typed client SDK package that other teams import to call your agent without hand-writing HTTP. make gen-proto regenerates the Python stubs from the .proto, and a gen-proto-check Continuous Integration (CI) step fails the build if the committed stubs drift from the contract. A gRPC server runs alongside FastAPI (default port 8087, multi-worker-safe via SO_REUSEPORT) and ships a standard gRPC health service out of the box:
On the calling side, LLM-Kit ships a channel provider so an agent never hardcodes an address. The auto provider tries Istio, then Consul, then a static fallback, health-checks the channel it selects, and runs a background monitor that re-selects after a few consecutive failures:
fromllm_kit.grpc.channel_providers.autoimport(AutoGrpcChannelProvider,AutoGrpcChannelProviderConfig,)provider=AutoGrpcChannelProvider(logger,AutoGrpcChannelProviderConfig(client_name="my-agent",service_key="some-internal-service",# resolved via Istio / Consul
enable_istio=True,enable_consul=True,))channel=provider.get_channel()# first healthy channel, auto-reselected on failure
stub=SomeServiceStub(channel)
This is the less glamorous side of being production-ready. Before an agent can deliver value, it needs to both accept calls from and make calls to the rest of the company’s services using the same transport the broader system already relies on.
What’s next
LLM-Kit solved building and shipping one agent. At 500 agents, the problems were no longer framework problems. They were platform problems: who can change which model everyone calls, how one team safely reuses another team’s tools, and how you know an agent got better and not just different after a prompt change. We built three answers for that layer: the GrabGPT Gateway, a remote MCP framework, and an evals platform. Part 2 starts with the gateway — one endpoint, five providers, and what it takes to make “swap the model” a configuration change instead of an incident.
Join us
Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
The most expensive part of a small feature request used to be writing the code. Now it’s usually the meeting about whether or not to write the code.
That’s a real shift, and it quietly breaks a lot of engineering instincts. Engineers learn early that most “small asks” aren’t small: they need tests, a rollout plan, someone to think through the edge cases and own the behavior after it ships. A two-hour change can become a two-week distraction if it touches the wrong part of the system. So we push back. Is this really needed? Does it belong in this release? Does it change a contract we already agreed to? I’m not giving that instinct up.
But it rests on an assumption that’s quietly breaking, which is that writing the first version of the code is the expensive step. For a specific class of change, it no longer is. If you can tell those changes apart from the rest, you can replace “is this in scope?” with a question you can answer in thirty minutes instead of a two-day debate.
The debate often costs more than the patch
Here’s a pattern I keep seeing. Someone asks for a small change such as surfacing a last_active_at timestamp that already exists in the backend on a settings page. The team spends forty minutes in a thread. One person says it sounds risky. Someone remembers a related migration from two years ago. Someone mentions the deadline. Eventually we land on “probably a day or two, could be more,” with low confidence, primarily because nobody has actually tried it.
That process made sense when trying was the expensive part. You had to stop what you were doing, load the context into your head, make the change by hand, write the tests, then discover the second- and third-order consequences. When the first attempt is cheap, defending the boundary can cost more than crossing it.
An agent can produce that first patch in the time the thread takes to warm up. It’s not free and definitely not automatically correct. But it is cheap enough that the smart move is often to stop guessing and look at a real diff.
The first patch is a price check, not the product
The mistake is to treat the generated patch as the deliverable. It isn’t. It’s a probe. It turns an abstract scope argument into a concrete artifact you can interrogate:
Does it touch the files you expected, or does it sprawl across five packages?
Are the tests obvious, or does the change resist being tested?
Does it preserve the existing abstractions?
Does it quietly require a new product decision?
Would you be comfortable owning this behavior six months from now?
Those are better questions than “does this feel like scope creep?” because now you’re arguing from evidence instead of vibes. If the last_active_at field comes back as a four-line diff with a passing test, ship it. The debate was the expensive part. However, if that same request comes back touching the auth middleware, you’ve learned the request was never small. Not only that, you learned this in thirty minutes instead of two days.
This is not letting the AI decide. It’s using the AI to make human judgment cheaper and better-informed.
Cheap to write is not the same as cheap to own
Here’s the trap, and it’s the most important distinction of the AI era. A change is not cheap just because the code was cheap to generate. It’s cheap only if a human can confidently review and own the result.
A thousand-line diff that technically passes but nobody wants to own is not a cheap change. It’s a deferred cost. So the dividing line in that case isn’t “can an agent write this?” It’s “can a person validate it?”
Adding a display field that already exists in the backend is usually cheap.
Changing authorization behavior is not cheap, no matter how clean the diff.
Refactoring a well-tested helper is usually cheap.
Changing data-retention semantics is not cheap.
Plenty of changes still deserve a hard no even when the code is trivial. This includes anything that moves the product contract, creates a support burden, or touches privacy, billing, or compliance. AI lowers the cost of producing a candidate. It does nothing to lower the cost of owning one.
Move scope discipline closer to the evidence
Traditionally, scope discipline happened before implementation, because implementation was the expensive thing to protect. Now some of that discipline can move to review. That doesn’t mean skipping planning. It means being precise about which planning actually pays off.
Before relitigating a small change, ask for a constrained attempt. The constraints are the whole point.
Produce the smallest possible patch. Keep it behind the existing feature flag. Don’t change the public contract. Add or update tests. List every file you touched and call out anything risky.
If the agent can’t produce a clean patch under those constraints, the request was bigger than you thought, and you know it carries a real ownership cost before anyone commits to it. If it can, that tells you something too. Either way you’ve replaced “is this in scope?” with “here’s what it costs. Do we want to pay it?”
The new skill is pricing uncertainty
The best engineers in an AI-assisted world won’t be the ones who say yes to everything, and they won’t be the ones who reflexively say no. They’ll be the ones who can price uncertainty fast. They’ll know when a request is a product decision wearing an implementation costume, when review will be harder than writing, and when a change is small enough that the fastest responsible answer is to just try it.
That last one is genuinely new. “Try it and see” used to mean pulling a developer off other work. Now, for the right kind of task, it means handing an agent a bounded assignment and using the result to make a better call. Less time guessing, more time supervising. Less time treating implementation as a black box, more time evaluating concrete artifacts.
Scope creep is still real. But “no, because any new code is too expensive” is a much weaker argument than it was two years ago. The cost of producing code has dropped. The cost of understanding, reviewing, and owning it didn’t. So the question worth asking shifted from “is this more work?” to “where’s the real cost?” And sometimes, for a small, bounded change, the real cost is just finding out.
The cost of saying yes has changed. The cost of saying no should change with it.
Give an agent better tools and it should do better work. That’s the instinct, anyway.
When you open a pull request, Copilot code review reads the diff and explores the surrounding code to find the problems that matter before they ship. To do that, it used its own code exploration tools. So when we swapped in the better-maintained, shared tools that power the Copilot CLI, grep, glob, and view, we expected a clean upgrade.
Instead, in our benchmarks, we found that the cost of reviews was higher and fewer issues were being caught.
But the tools weren’t the problem. The instructions were. Once we rewrote them for the way a reviewer actually reads a pull request, the regression flipped into a win: roughly 20% lower average review cost, while maintaining the same review quality.
This is the story of how adjusting the workflows around the tools led us to a fix.
Same tools, wrong instincts
If you’ve built on top of an agent framework, you’ve probably inherited its tools too. They work, so you keep them, until the day your use case drifts far enough from what they were designed for that they quietly start working against you. That’s the situation we were in. Before trying to use the shared CLI tools, Copilot code review used its own code exploration tools. That tool layer was inspired by earlier agentic systems, including ideas from SWE-agent-style repository navigation and GitHub Copilot Autofix: list directories, search files, search directories, and read code. Those tools worked, but they were specific to Copilot code review, and they were designed for how models behaved at the time. Earlier agentic coding models made fewer tool calls and were worse at automatically pulling in necessary context. This meant it was more important to include all relevant information in the few tool calls that the model made.
Meanwhile, the Copilot CLI harness has a shared set of Unix-inspired code exploration tools: grep, glob, and view. That harness is also used by a growing number of Copilot agent products, including GitHub Copilot cloud agent, so harness improvements can benefit more than one product. We wanted to clean up and share infrastructure where possible, so we experimented with using the tools from the Copilot CLI harness in Copilot code review. The goal was to reduce duplicated tool implementations, create one shared place to improve code exploration tools, and make it easier to carry those improvements across Copilot products.
On paper, the migration looked simple:
Old Copilot code review
GitHub Copilot CLI
Purpose
list_dir
glob
Discover candidate files and directories before opening code.
search_file and search_dir
grep
Search code for matching text, symbols, or call sites.
read_code
view
Read the relevant file contents once a path or range is known.
The existing review tools were not thin wrappers. When searching for a directory or reading a code range, they could return the matched or requested lines plus extra surrounding code context. That added token cost, but it also matched how earlier models often benefited from having nearby context included automatically.
Initially, we hoped this would be a simple migration: swap one set of tools for another. But when we tested the shared tools in offline benchmarks, the review agent became less efficient and less effective. Average cost increased, and the number of useful comments dropped.
The trace revealed a browsing loop
Our internal Copilot code review benchmarks were useful because they show more than a final score. They show the path the agent took, including which tools it called, how much output came back, where errors happened, and whether it was narrowing toward evidence or widening the search.
When we first tried the shared Copilot CLI tools in offline benchmarks, the agent often behaved as if it was browsing a repository instead of investigating a pull request. It would search broadly, guess likely paths, read broadly, find more things to search, and carry that extra context forward.
Figure 1: Before — a simplified illustration of the general-purpose behavior we observed: widening the search, guessing paths, and accumulating context.
That pattern is understandable. Broad exploration can be useful when the task is “understand this repo.” But it’s not how a reviewer would usually review a pull request.
When I review a pull request, I start from the diff and ask targeted questions:
Where is this function called?
Is this config key used anywhere else?
Is there a test or helper with the same pattern?
What is the smallest nearby code range that explains this behavior?
I do not want to open a large part of the repository before I know what I am looking for. I want the minimal context needed to answer the question, without overloading the review with unrelated code.
That matters because every tool result becomes part of the agent’s working context. Extra file contents can be carried forward into later reasoning, increasing cost and sometimes making the review less focused. A tool result is not a disposable printout; for an agent, it’s extra tokens that stay in the context window.
The traces made that difference visible. The shared tools were not the problem. The instructions were giving the agent the wrong instincts to do an efficient and effective review.
The tools themselves worked, but their instructions were tuned for their use within the Copilot CLI and implied the wrong workflow: the agent used grep, glob, and view like a broad coding assistant instead of a reviewer. A coding assistant may map a whole area before making a change to ensure it doesn’t break some other corner of the code. On the other hand, a reviewer usually starts from the diff, asks whether the change introduced a problem, and then looks for the narrowest nearby evidence required to confirm or dismiss it.
General coding-assistant tool instructions, like the ones used by Copilot CLI or Copilot cloud agent, make sense for an interactive assistant. A developer may ask it to understand a repository, plan a change, edit files, and continue over multiple turns.
Copilot code review has a narrower job: start from a pull request diff, gather enough surrounding evidence to decide whether a change introduces a real issue, and avoid loading context that is not needed for that review question.
It was therefore clear that we couldn’t simply replace the previous Copilot code review tools with the tools from the Copilot CLI without additional prompting work. The problem became: how do we design tool instructions that use these shared tools effectively in a code review setting?
Rewriting the tool instructions for a reviewer’s workflow
The next iterations made the guidance specific to code review. The workflow we wanted Copilot code review to follow was:
Start from the diff and form specific review questions.
Use glob when the path is uncertain and grep to find candidate files, symbols, and call sites.
Batch cheap discovery before reading files.
Use view only when the agent knows which file or line range it needs.
Batch focused reads instead of alternating between one search and one read.
In oversimplified form, this was the behavior we encoded:
Generic posture: Use the available tools to inspect repository context that may be relevant.
Review-shaped guidance: Start from the diff. Narrow first with grep and glob; read exact evidence with view. If grep fails to find relevant context, retry with a simpler escaped search. If a path is wrong, pivot to glob instead of guessing nearby paths.
For example, imagine the diff changes an authorization helper that decides whether an operation is allowed. A relevant review question is not “show me the full contents of every file that calls this helper.” It could instead be the narrower: “are any request-handling callers relying on the old behavior?”
The intended path is short:
start from the helper changed in the diff
grep for callers of that helper
glob for likely route, handler, or controller files
view the most relevant caller ranges
decide whether any caller changes the risk
The guidance also changed how the agent recovered from failed searches. If an input made grep fail, the better next step was one simpler, corrected search. If a path was wrong, the better next step was glob, not guessing neighboring paths and reading whatever happened to exist. That nudged the agent away from letting a small tool failure turn into a larger exploration loop.
Figure 2: After — a simplified illustration of the review-shaped behavior the prompt guided toward: stay anchored to the diff, narrow with grep and glob, then read focused ranges with view.
The change was small in wording and large in effect. It changed the rhythm of the agent from “browse, read, search again” to “ask, narrow, read, decide.”
Benchmarks let us debug behavior, not just scores
The shared harness gave us the tools. The internal Copilot code review benchmarks gave us the feedback loop.
We could run the same review examples, compare tool traces, update the instructions, and run again. That let us ask concrete questions:
Did the agent narrow first, or read broadly first?
Did it batch independent searches?
Did it call view only when it had a reason?
Did a tool-instruction change reduce tool errors, or just move them somewhere else?
Did the trace stay focused on evidence from the diff?
Did the review still preserve the quality metrics we cared about?
The most useful signal was not “the instructions are better.” It was more concrete. The agent was making a similar number of tool calls, but spending more of them on relevant evidence instead of repeatedly expanding the search.
That connected product-level outcomes to understandable engineering behavior. Instead of guessing why a score moved, we could inspect the workflow that produced it.
The result: roughly 20% lower average review cost
In production, the tuned behavior showed roughly 20% lower average review cost compared with the control. Importantly, it did not show a quality signal that could block shipping.
The reduction did not come from the tools by themselves, it came from the workflow around them. Shared code exploration tools, Copilot code review custom tool instructions, and internal benchmarks made the agent’s behavior visible enough to tune.
That framing matters when building with agents. It can be tempting to treat tools as implementation details by swapping one tool for another, then comparing the final answer. But for an agent, the tool surface is part of the product experience. It changes what the agent notices, how it searches, how much context it carries forward, and when it decides it has enough evidence.
Tool descriptions and system instructions are closer to API documentation. Unclear API docs can leave a developer confused and lead to inefficient or wrong decisions. Unclear tool prompting can do the same for an LLM; a small wording change can affect cost, quality, and the shape of the investigation because it changes how the agent spends its attention.
Same tools, different job
We also tried to apply the same kind of focused tool instructions in the CLI, where it did not produce the same kind of win. That is a useful counterexample, and an important guardrail for the lesson.
Copilot code review is anchored to a diff and a review question. Copilot CLI handles broader, interactive coding tasks where exploration can be part of the job. There may be no single diff anchor, the user may change direction over multiple turns, and the right context may not be obvious at the start. The same grep, glob, and view tools can support both products, but the workflow around those tools has to match the product.
The takeaway is that shared tools scale when the instructions and benchmarks match the job.
At Grab’s scale, managing petabytes of data across billions of S3 objects demands more than a storage layer. It demands a robust architectural primitive that supports the high-concurrency needs of a modern “Lakehouse.” Our goal is full storage-compute separation, leveraging S3 as an elastic foundation for both near-real-time metrics and large-scale batch transformations.
For years, the vast majority of our tables were Hive Parquet, managed through the Hive Metastore with a directory-based layout. This model served us well, but as data volume grew, the directory-and-metastore approach became the limiting factor. We are now transitioning to a table-centric architecture built on modern table formats, treating data as a first-class primitive to ensure consistency and performance across our internal data transformation platforms: Slide, which powers batch transformations, and Hugo, which handles online-to-data-lake ingestion. Along the way, we also built the UnifiedSparkCatalog, a unified Spark catalog that hides table-format differences from users entirely, which we are open-sourcing alongside this post.
The catalyst for change: Challenges with Hive Parquet
For years, Hive Parquet was the backbone of our Data Lake, representing the vast majority of our tables. However, as data volume scaled, the architectural limitations of directory-based storage became apparent. We identified four primary bottlenecks:
Catalog latency: The Hive Metastore (HMS) became a centralized failure point. High concurrency during metadata access led to O(n) listing overhead, where query planning time scaled linearly with partition count, crippling throughput.
The small file problem: The directory layout left us with severe file fragmentation. Certain Machine Learning (ML) datasets had an average file size under 1 MB, with thousands of files in each partition. At this scale, the overhead of S3 object listing and metadata request latency drove up Application Programming Interface (API) costs and slowed scan operations.
Operational toil: Data engineers faced constant manual overhead for partition registration. Without native ACID support (no native UPSERT or DELETE), teams relied on complex workarounds to manage data changes carefully.
The broken information loop: A fundamental disconnect existed between the catalog and storage. Because the HMS, not the storage layer, was treated as the source of truth, direct S3 modifications frequently left the catalog stale and out of sync with the actual state on disk.
Why Iceberg? Strategic alignment and future-proofing
We evaluated several open table formats before selecting Apache Iceberg as our default. The deciding factors came down to community governance, engine compatibility, and long-term flexibility.
Recent industry momentum, including growing cloud-native support for Iceberg, further validates this direction. We are positioning Grab to be format-agnostic in the long term, but Iceberg provides the most mature foundation today.
Adopting Iceberg at scale
Migrating an established lake is not a flag flip. Our challenge was rolling out Iceberg across a lake that was overwhelmingly Hive Parquet, queried by many engines and teams, without breaking the downstream consumers that depended on those tables. Rather than converting everything at once, we moved the highest-value tables first. The efficiency gains across our production workloads have been substantial. Here are representative examples:
Query performance via Z-ordering: On a high-traffic navigation dataset, we achieved roughly a 10x improvement in query runtime. Z-ordering co-locates rows with similar values across specified dimensions, enabling Trino to leverage data skipping and min/max statistics to prune irrelevant files during query planning. This reduced query runtime from 70 seconds to 6 seconds.
S3 API cost reduction: For a heavily queried operations table, daily S3 API costs were reduced by up to 95% with no changes to the queries themselves. Larger file sizes and the elimination of expensive object listing during query planning drove most of the savings.
Compute savings: For a dataset used in funnel analysis, we reduced cluster resource usage by approximately half. A separate ML feature pipeline also improved feature freshness for downstream models.
The UnifiedSparkCatalog: Making mixed formats transparent
Migrating to Iceberg solved our storage and metadata problems, but it surfaced a new one at the developer-experience layer. Modern table formats like Delta, Iceberg, and Hudi each implement their own custom catalog that extends Spark’s SessionCatalog. In a standard Spark runtime, only one catalog implementation can be set as the default spark_catalog. Supporting additional formats requires explicit catalog declarations, meaning users must reference tables with format-specific prefixes like iceberg_catalog.schema.table or delta_catalog.schema.table.
With Iceberg, Delta, Hudi, and Hive tables now coexisting and tables actively migrating between formats, this created two problems: engineers had to know the underlying format of every table they queried, and any format migration silently broke every downstream query that hardcoded a prefix.
The UnifiedSparkCatalog is our answer. It is a unified Spark catalog that abstracts the complexity of working with mixed table formats so users never need to think about which format a table uses. We took inspiration from Trino’s Table Redirection, a feature that transparently points a query at the right connector when a table’s format differs from the catalog it was queried through. Our Spark equivalent works as follows:
How it works
Table detection: The catalog loads metadata from the Hive Metastore.
Format identification: A TableTypeDetector utility identifies the format based on metadata properties (e.g., the provider field) or path-based inference.
Operation routing: The catalog delegates the operation to the correct format-specific catalog (Iceberg’s SparkCatalog, Delta’s DeltaCatalog, etc.) without requiring any prefix from the user.
Key design decisions
Lazy initialization: Catalogs for each format are initialized only when first needed, reducing startup overhead. If a format’s JAR is missing from the classpath, initialization continues gracefully. The catalog simply skips that format rather than failing the entire session.
Naming as spark_catalog: The catalog reports its name as spark_catalog because Spark treats this name specially for legacy Hive Data Manipulation Language (DML) operations. Many internal Spark code paths check for this exact name to determine whether to use Hive-compatible logic for inserts, updates, and deletes. Using any other name would break legacy Hive table operations.
Catalog reuse: Before creating a new catalog instance, the system checks whether one already exists in Spark’s catalog manager. This preserves compatibility with plugins like OpenLineage, which inspect catalog class types for lineage extraction.
Fallback behavior: If a table is not found in the expected format-specific catalog, the system falls back to the base session catalog, ensuring robust behavior for standard Hive tables.
We are open-sourcing UnifiedSparkCatalog alongside this blog post. The code and documentation are available here.
Lessons learned and overcoming hurdles
Scaling Iceberg across a large ecosystem revealed several technical nuances:
Hive lock contention: We encountered “zombie locks” in the HMS that blocked commits. We traced this to a low read timeout on the metastore side under high load. Adjusting retry intervals and increasing the timeout resolved the issue.
Timestamp handling: Spark 3.4 introduced TIMESTAMP_NTZ (no time zone), while Iceberg defaults to TIMESTAMP_LTZ (local time zone). This caused compatibility issues with legacy Hive views. We resolved it through a custom migration workflow and targeted patches to our Trino deployment to ensure consistent casting.
Storage tier costs: Generating Iceberg metadata involves reading historical data, which can trigger a one-time cost spike as files move between S3 storage tiers. To manage this, we prioritize migrations based on a table’s scan frequency and API operation costs rather than migrating the entire lake at once.
Conclusion: The road ahead
Apache Iceberg is now foundational to Grab’s data strategy. It is the default format for Slide and Hugo, and adoption is expanding across our compute platforms.
Looking forward, we are experimenting with Storage Partitioned Joins to eliminate shuffle stages in Spark and monitoring the Apache XTable project to maintain interoperability between formats. Our journey does not end with adoption. We will continue contributing back to the ecosystem, starting with the upcoming release of the UnifiedSparkCatalog.
Acknowledgments: This journey was made possible by the dedicated efforts of the Data Engineering, Infrastructure, and Search & Personalization teams at Grab.
Join us
Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
“Where are the docs?” It’s a question nobody on a product team enjoys answering. The honest reply is usually some variant of “behind.” A writer is staring at a closed pull request, trying to reverse-engineer what changed. The pull request’s author has already moved on. By the time the doc actually publishes, the feature has shipped, sometimes more than once.
That used to be us on the Aspire team (we’re a small team of 10 building dev tools for distributed apps). A few months back, we were trying to figure out how to safely bring AI into automations we already trusted. That’s when we discovered GitHub Agentic Workflows. I started bolting prototypes into microsoft/aspire.
Here’s what that bought us, in numbers pulled straight out of GitHub: for Aspire 13.3 and 13.4, 82 feature-docs pull requests merged at a median of 44.8 hours after the product pull request, every one of them reviewed by the engineer who shipped the feature. No new headcount. No process retraining. Just a different way of asking “who writes this?”
🔒 The constraint: cross-repo automation is the hard part
Our product lives in microsoft/aspire and our docs site lives in microsoft/aspire.dev—different repo, deploy target, and review chain. Most teams figure out same-repo automation pretty quickly; cross-repo automation is where things get sharp. Broad repo-scoped tokens belong in a museum, and any responsible security posture (ours included) restricts them accordingly. That’s a good thing. It’s also a real bottleneck if the place where you write the docs isn’t the place where you write the code.
The default workflow for years was:
Engineer ships a feature in microsoft/aspire.
Docs writer notices weeks later.
Docs writer opens the pull request, reads the diff, and pings the engineer to clarify what changed.
Engineer is on the next feature, vaguely remembers, replies with half the picture.
Docs draft ships, sometimes against a release that’s already out.
This is the reverse-engineering tax. We needed automation that crossed repos without handing an agent a write-everywhere token. GitHub Agentic Workflows turned out to be the answer.
🤖 Why GitHub Agentic Workflows
GitHub Agentic Workflows is a project from the GitHub Next team that I keep describing to people as “GitHub Actions, but with a model as the work-item processor and guard rails that satisfy security review.” That’s reductive, but it’s close.
The shape of it:
You author a workflow as a single markdown file (.github/workflows/my-thing.md). YAML-style frontmatter on top, an English-language prompt underneath.
You run GitHub Agentic Workflows compile, and it generates a sibling .lock.yml (a normal GitHub Actions workflow) that you commit alongside.
At runtime, the workflow runs an agent against your prompt with a constrained toolset.
Critically, the agent doesn’t write to GitHub directly. It emits intent (a JSON blob describing the pull requests, issues, and comments it wants to create), and a separate, narrowly scoped job (the safe-outputs handler) materializes that intent against a per-workflow GitHub app.
That last bullet is the unlock. The agent gets read access and a prompt. Writes go through a tiny verifiable pipeline with explicit allow-lists. Security review nods. We ship.
💚 A small aside: kindred stacks
I love when the tools you’re using to build are built with the same tools you’re using to build with. The GitHub Agentic Workflows docs are built with Astro and Starlight. So is aspire.dev—Astro with Starlight, dressed up with the wider Starlight plugin ecosystem (astro-mermaid, starlight-llms-txt, starlight-sidebar-topics, starlight-image-zoom, the gorgeous @catppuccin/starlight theme, and more. Shout-out to Chris Swithinbank and the Starlight maintainers, the entire ecosystem feels designed by people who genuinely care).
There’s a real kinship there. The tool we use to automate docs and the docs site we automate into share the same foundation. Convenient, because the Mermaid sequence diagram in the next section renders the exact same way in both worlds.
The end-to-end pipeline
Here’s the flow we landed on. The protagonist is a workflow called pr-docs-check.md living in microsoft/aspire.
A run starts on pull_request: closed against main or release/*, gated by merged == true. From there, the workflow first runs a deterministic target branch resolver in plain bash before the agent ever wakes up:
Pull request milestone title (e.g. 13.4 → release/13.4 on aspire.dev).
Linked-issue milestone title (parse Fixes/Closes/Resolves #N from the body, fetch each issue, take the first non-empty milestone).
Pull request base ref, if it matches release/X.Y[.Z].
Fall back to main.
This is the linchpin. Milestones in the product repo map cleanly to release branches in the docs repo. When the agent finally runs, it knows exactly where the docs should land without any creative writing about target branches or guessing.
The agent reads the diff, scans linked issues, and decides: does this need docs? If yes, it drafts the actual content in a checked-out microsoft/aspire.dev workspace, following our existing doc-writer skill (voice, MDX conventions, Starlight components). It then emits a create_pull_request safe-output and hands off.
The safe-outputs handler takes over:
Title prefix: [docs]
Label: docs-from-code
draft: true (we never auto-merge)
Base branch: agent-supplied, restricted to main or release/*
Target repo: microsoft/aspire.dev
Reviewer: the SME identified from the source pull request’s reviews—i.e., whoever the product team trusted to approve the feature, now gets asked to approve the doc for that feature.
A companion job posts a marker comment back on the source pull request with the docs pull request link and minimizes any older pr-docs-check comments on re-run. The engineer who just hit Merge gets a notification within a few minutes: “Here’s the docs draft. Look it over?”
🔐 The safe-outputs contract
The whole security story comes down to a small, boring stretch of frontmatter:
That’s the deal in plain text. The agent gets a GitHub App token whose installation is scoped to exactly two repositories—the product repo and the docs repo—and nothing else in the org is reachable. It can only land pull requests against main or release/*. AGENTS.md and dependency manifests are off-limits by policy. If the pull request creation fails (network blip, conflict, anything), the framework falls back to filing an issue, so nothing is silently dropped.
This is the part security review actually liked. The agent’s reasoning is fuzzy. The action surface is not.
📊 By the numbers
Here are the stats from a rolling 30-day window (May 3 – June 2, 2026) spanning the back end of the Aspire 13.3 release and the run-up to 13.4:
Metric
Value
Product pull requests merged in microsoft/aspire
396 (338 main / 50 release/13.3 / 8 release/13.2)
pr-docs-check workflow runs
396
Draft docs pull requests created on microsoft/aspire.dev
82
– Merged
82 (100%)
– Closed without merge
0
– Still open
0
Docs pull requests target branches
52 → release/13.3, 27 → release/13.4, 3 → main
Median time-to-merge (docs)
44.8 hours
Merged within 24 h / 7 days
38% / 96%
Note: Numbers captured at the time of writing; the workflows keep running, so the totals only go up.
A few of those numbers deserve a second look:
396 runs → 82 pull requests is not a defect. The workflow runs on every merged pull request; most of them are internal refactors, test fixes, or dependency bumps with no user-facing surface. The agent saying “no docs needed” 300+ times is a feature.
100% merge rate says the agent’s docs picks are right. The tighter prompt we shipped after the v1 false-positive phase is paying off.
✅ What worked, ❌ what didn’t
What worked
✅ Milestone → release-branch mapping. This was the single highest-leverage choice we made. Engineers already set milestones on pull requests and issues; we got accurate target-branch routing for free.
✅ Draft-only, SME-as-reviewer. The agent never merges. The engineer who shipped the feature is the one who confirms the docs are right. We’ve stopped reverse-engineering features at the doc layer. The engineer just tells the docs draft what to say, in the place where they already are.
✅ Scoped GitHub app per workflow. Each workflow gets its own app token with explicit repo and permission scopes. Security review approved. We approved too; the first time we needed to rotate keys.
✅ protected-files: blocked. The agent cannot touch AGENTS.md, package manifests, or repo security config. Period.
What didn’t (at first)
❌ The agent’s “is this docs-worthy?” gate was too generous in the first version. It drafted pull requests for changes that were genuinely internal, such as a CI tweak or a logging refactor. The result: 9 closures of 69 pull requests (≈13%), so we tightened the prompt’s user-facing-change definition and added explicit negative examples (CI, internal helpers, tests-only). Now, the rate is trending down.
❌ Cross-repo pull request creation needed a mirrored checkout pattern that wasn’t obvious from the docs. The agent works in one repo; safe-outputs needs to find the target repo to push a branch. We solved it by checking out microsoft/aspire.dev twice—once as the current workspace, once under _repos/aspire.dev—so the safe-outputs handler can rediscover it deterministically.
❌ Big diffs blow prompt budgets. We pre-extract pull request metadata (linked issues, milestone, base ref) in pre-agent-steps bash, so the agent gets a small, structured summary instead of a giant payload. This is GitHub Agentic Workflow’s designed-in pattern, and it works.
Wrapping up
The changes we made shifted our thinking. A feature wasn’t considered done until the docs were. Docs no longer trail along behind it like a tin can on a string. The engineer’s review is the gate; the bot does the typing.
Critically, this doesn’t replace docs writers; it un-burdens them. Our writers used to spend most of their time reverse-engineering features. Now they spend their time on the things only a human can do well: narrative pages, sample programs, conceptual walkthroughs, the parts of the docs that don’t fall out of a diff. The bot handles the mechanical “this new option was added; here’s the reference page update” work that was never enjoyable for anyone.
Huge thanks to the GitHub Next team for GitHub Agentic Workflows (and for making the safe-outputs primitive a first-class part of the design), and to Chris Swithinbank and the Starlight maintainers for the docs platform we automate into. A genuine thank-you, too, to the security folks whose guardrails forced us to design this the right way the first time. The boring secret of good automation is that strong security constraints make the system more trustworthy and more correct.
If you build a product in one repo and ship docs in another—and especially if you have to do it inside any nontrivial security boundary—GitHub Agentic Workflows is worth a serious look. Start with one workflow, such as pr-docs-check, and watch what happens to your median time-to-docs.
🔗 The other workflows
pr-docs-check is the one I wrote this post about, but it’s not running alone. If you’re curious about the rest, the source is public:
milestone-changelog.md: runs every two hours, picks up newly merged pull requests in the active milestone, and maintains a 13.x-Change-log wiki page (new features, improvements, notable bug fixes) with a companion editorial-feedback issue. 346 runs.
release-update-support-mdx.md: on a stable Aspire release, drafts a [support] pull request on aspire.dev that updates the support policy page (promotes the new version, demotes the previous one, refreshes the “Last updated” badge).
update-integration-data.md: lives in the docs repo; runs pnpm update:all daily, refreshes NuGet metadata + GitHub stats + sample data, and opens a chore: Update integration data PR with supersede-and-close logic for stale runs. 27 runs, eight merged pull requests.
repo-pulse.md: a rolling three-day repo dashboard pinned to a single issue and updated in place: recent merges, pull requests awaiting review, new issues, discussion activity. One issue, always fresh.
Counter Service is used across Grab’s anti-fraud platform to answer time-windowed count questions, such as recent ride requests by a user or failed payment attempts on a card. The service handles tens of thousands of queries per second (QPS) with about a billion requests per day, while maintaining strict requirements around latency and reliability to support real-time fraud rule evaluation.
For most of its life, Counter Service was backed by a wide-column database that served the workload reliably as the service scaled. As part of a broader infrastructure review mandated at an organizational level, our database team evaluated alternatives to this storage that many services relied on, including Counter Service. Based on their assessment, Aerospike emerged as a good fit for our use-case. We also used the migration as an opportunity to decouple storage concerns from business logic, a necessary first step for this migration, and one that would reduce the effort required for future storage changes. As part of the same effort, we revisited the data model and access patterns in detail, which helped us identify and apply several straightforward optimizations.
This post walks through how we did it. What we built on the reader-side to make the migration safe, how we redesigned the writer-side data model around the new backend, and what we ran into during the gradual rollout.
Setting the stage
Counter data is stored in three time granularities: 15-minute, hourly, and daily buckets. A typical read would be along the lines of, “give me the count for key X over the last 90 minutes”, which the service decomposes into the smallest possible set of buckets, one hourly in the middle, a few 15-minute buckets at the edges, fetches them, and sums.
In the original setup, each granularity was stored in a separate table with a composite primary key:
The clustering column gave us convenient range queries, that is needed for the Counter Service. On the write path, each incoming counter event triggered a read-modify-write, three parallel SELECT across the three tables, an in-memory increment, then a batch write. This produced four network round-trips per event.
As this service is a core part of Grab’s fraud detection ecosystem and handles high query volume, migrating its underlying storage required a careful rollout plan. We had three requirements:
Ramp traffic to the new backend gradually and roll back at any point with a config change.
Monitor both the original and new storage paths to verify data integrity before switching over.
Complete the migration without downtime.
We also wanted the migration machinery to be reusable for future storage changes. The migration is divided into three workstreams, which we’ll walk through below:
Preparing the reader service.
Identifying the best integration mechanism for the new storage.
Updating the writer pipeline.
Reader: Separating the data access layer
The reader is a Rust service. Before any migration work began, the reader’s business logic had tight coupling with the storage layer. Session creation, query building, fan-out orchestration, and the data types those queries returned were all intertwined in a single flat file. The main application state struct (AppState) held a raw database session handle and prepared query references. Every handler, gRPC Remote Procedure Calls (gRPC) or HyperText Transfer Protocol (HTTP), received the bare session as a parameter. Variable names baked the storage technology into the business layer.
This made the storage migration difficult to attempt directly. We couldn’t add a second storage backend without forking the orchestration logic, and we had no way to test the read path in isolation from a real database session. So we did the migration prep in three stages.
Stage 1: Extracting the storage code
The first stage shipped no behavioural change. We deleted the monolithic storage file and split its contents in two:
storage/legacy.rs: wrapped session creation, prepared statements, and query execution behind a LegacyStorage struct.
batch_read_ops.rs: kept only the orchestration logic: time-range splitting, channel-based fan-out, and aggregation.
AppState started holding an Arc<LegacyStorage> instead of a raw session handle. The PreparedQueries struct lost its statements (those moved inside LegacyStorage). We renamed every storage-specific identifier in business code to generic storage_* names.
The result was a hard fence. After Stage 1, the database driver crate was reachable only from inside the storage module. Nothing in the business logic or handlers imported it any more.
Stage 2: The storage facade
With the seam in place, we introduced the actual abstraction. A new storage/ module with mod.rs, legacy.rs, aerospike.rs, and mock_storage.rs as siblings became the only place driver crates were reachable from.
The idiomatic Rust approach would have been a trait with associated types, but our backend selection is runtime (a config string parsed at startup), and associated types propagate upwards through every consumer. The alternative, trait objects with boxed futures adds a heap allocation per query, which we wanted to avoid at our QPS.
A match statement at the request boundary, which made it easier to reason about and debug. The facade then routes everything to the original backend without the rest of the code knowing or caring.
Each backend’s execute_queries honours the same contract: take a Vec<QueryCandidate> and a HashMap<BatchIndex, Sender<...>>, and emit (index, value, timestamp, granularity) tuples into those channels. The orchestration layer above doesn’t need to know whether a candidate became a paginated row stream or a single batch read with client-side map filtering, both write into the same channels in the same shape.
On top of the facade we layered three config-driven operating modes that map to the migration phases:
Single: one backend serves the request.
WithShadow: the primary serves the response; the secondary runs asynchronously in the background for parity comparison.
WithSplit: a deterministic percentage of traffic is served by each backend. Used for the live cutover.
The mode and traffic percentages are read from a service config, allowing the reader to move from legacy-only to Aerospike-only without code changes. The transition starts in Single(legacy), then shadow reads are enabled with WithShadow(primary=legacy, secondary=aerospike, pct=X). The shadow percentage is gradually ramped from 5% to 20%, 50%, and finally 100%, while parity is verified through metrics. Optionally, the system can then move into WithSplit(primary=legacy, secondary=aerospike, split=X), where live traffic is gradually shifted from the original backend to Aerospike, for example from 5% to 30%, 70%, and then 100%. Once Aerospike is fully validated and serving all traffic, the reader moves to Single(aerospike).
Stage 3: Shadow comparison and metrics
Each storage call carries metadata like backend, role (primary/secondary/shadow), and mode, attached as tags to every metric. When Aerospike was added, existing dashboards showed per-backend breakdowns without changes.
We placed the mode dispatch at the handler level rather than inside the storage layer to validate the full request path, not only the rows returned by storage. This also lets the response return as soon as the primary completes, while the shadow runs as a fire-and-forget background task.
Writer: redesigning the data model
Since the two systems use different storage engines, it wasn’t clear that a one-to-one port of our original schema would work. We tried three approaches.
Approaches 1 and 2: Row-per-bucket
We first tried mirroring our original row-per-bucket model. Approach 1 used Aerospike’s Secondary Index (SI) to recover range queries; approach 2 skipped SI and computed the exact set of primary keys client-side via BatchGet.
Both hit the same wall: Aerospike’s primary index is 64 bytes per record, kept in memory. At billions of records, index memory becomes the constraint. SI added overhead and operational complexity we didn’t need.
Approach 3: Map-based schema
The third approach was structurally different from the first two and was the most compact of the options. Rather than storing one record per bucket, which kept us in the same cardinality regime, we collapsed all bucket counts for a single counter into one record. The values were stored as a sorted map keyed by bucket timestamp:
The map keys are bucket timestamps in milliseconds. The map values are running counts. One record holds the entire time series for one counter at one granularity.
Reads become straightforward: fetch the record, iterate the map, sum the entries within the requested window. Each Get returns a bounded number of map entries (determined by Time To Live (TTL) and bucket size), and client-side filtering of that many entries is negligible.
Writes use MapIncrementOp, an atomic server-side increment of a value at a given map key, creating the entry on first access. Combined with MapRemoveByKeyRangeOp for pruning stale entries, every write is one atomic operation:
For TTL management, we couldn’t use Aerospike’s record-level expiry directly. A single record holds many timestamps, so record-level TTL would either keep everything or drop everything. Instead, we prune stale map entries explicitly on every write using MapRemoveByKeyRangeOp. The record-level TTL stays as a safety net for counters that stop receiving writes.
The two backends produce very different network shapes for the same logical query. The original backend returns many small paginated row streams, one per (key, granularity). The server filters by time range using the clustering column. Aerospike returns one batch response with the entire counts map per key, and the client filters the map to the requested range. The reader’s storage layer hides this difference: both paths emit (index, value, timestamp, granularity) tuples into the same per-index channels, and the orchestrator above sums them the same way.
The third approach performed best in testing. By collapsing many bucket records into a single record per counter, we reduced the total record count by more than an order of magnitude, which also reduced primary index memory. It also produced a smaller on-disk footprint, since the long counter key is stored once per record instead of being repeated across every bucket. The schema was chosen to fit the access pattern, with the index and disk savings following naturally.
The pipeline continues writing to the original backend as the primary, while Aerospike is added as a separate asynchronous shadow write behind a deterministic rollout logic. This lets us ramp Aerospike gradually and eventually cut over to it fully.
Reader: How each backend actually serves a query
The two storage backends sit behind the same execute_queries contract on the reader service, but what they do internally for a single batch read looks very different.
Figure 1. How a single read request flows through each backend.
The reader takes a batch of counter queries and decomposes each into one or more sub-queries per granularity (a 90-minute window for instance, becomes one hourly sub-query and two 15-minute sub-queries). In the original backend, each sub-query becomes its own prepared statement bound with (start_ms, end_ms, key), and the storage layer fires all of them concurrently as a stream of futures with buffer_unordered capping in-flight queries to a tuned bound. Each query returns a paginated row iterator, the server uses the clustering column to filter by time range and rows stream through to per-index channels as they arrive. So a single user request can produce many small queries, each a separate network round-trip to the partition master holding key, with results dribbled back over a paginated stream.
On Aerospike, the storage layer first groups all sub-queries by granularity, then issues one BatchOperate per granularity. Each sub-query becomes a single primary-key read against the appropriate set; the server returns the entire counts map for that key in one record. The client iterates the map and emits only the entries whose timestamps fall inside the requested range. This keeps the code simple, and at our map sizes the overhead is negligible. There’s no streaming, a batch read either succeeds or fails as a unit and there are at most three network round-trips per user request, one per granularity, regardless of how many sub-queries there are.
This reflects the different design philosophies of the two systems. Wide-column stores typically expect client-side fan-out for reads, while Aerospike’s batch API is designed for exactly this multi-key pattern.
A few issues with the Aerospike Rust client also surfaced during rollout, as it was less mature than its Go counterpart. For example, when we started, the officially available Rust client was synchronous, so every batch read had to be bridged through tokio::task::spawn_blocking with some amount of custom plumbing. Once the official async client was released, we removed that layer and saw measurable improvements in both p50 and p99 latency. The other issue was Domain Name System (DNS). The client resolved seed hostnames only during initialization and did not re-resolve them when the cluster topology refreshed. As a result, a full staging cluster replacement, with new IPs behind the same hostnames, left the client stuck on the old IPs until restart. We filed the bug upstream, and a fix shipped in a subsequent release. We also reproduced the scenario locally with a Docker-based end-to-end test and ran additional staging drills to confirm recovery before continuing the rollout.
Experiment with indexing
We run Aerospike in its default storage configuration, Hybrid Memory Architecture (HMA), where the primary index sits in Random-Access Memory (RAM) and the data sits on Solid-State Drive (SSD). The other relevant mode keeps both index and data in Dynamic Random-Access Memory (DRAM), which is more expensive and not something that fits our use-case. Even in HMA, the primary index grows linearly with record count. At our scale, that growth was a foreseeable issue.
To raise the memory ceiling, we tried moving the primary index itself from RAM to local Non-Volatile Memory Express (NVMe) while keeping data on SSD. We expected the extra index latency to be invisible within our overall request budget. In practice, we started seeing p99 spikes that did not track overall QPS. Instead, they followed I/O activity on hot keys. We observed that when many concurrent lookups land on the same record, the in-memory index handles them more prudently compared to a disk backed index. Adding more and better nodes improved things slightly but did not mitigate the issue. Consequently, we reverted back to in-memory index with a memory-optimized instance type.
Overall impact
The migration delivered gains across infrastructure, performance, and data footprint. Most of these improvements trace back to the schema redesign like collapsing rows into maps, rather than the database change itself.
The primary index currently uses about 50 GB of the roughly 100 GB usable memory per node. The same dataset is around 1 TB on disk, compared with around 3 TB on the original setup. This is primarily attributed to our adoption of the map-based schema discussed earlier.
In production, p99 read latency was consistently better than the original setup, with roughly 50% improvement across our read paths. The write path now uses a single atomic increment operation, replacing the read-modify-write pattern we had built previously.
The new setup costs roughly 45–50% less per node compared to our original setup. We also reduced the replication factor from 3 to 2, saving roughly a third of both storage and primary index memory. RF=2 can be awkward in databases that depend on write quorum, but Aerospike’s master-replica model still keeps an authoritative copy available after a single-node loss. That gives us meaningful fault tolerance even at RF=2. The remaining risk, a simultaneous multi-AZ failure, was acceptable for this workload because the writer continues producing increments from the source event stream. Any lost counter data can self-heal as new events arrive.
Conclusion
This migration ultimately came down to aligning the storage design with the workload. These results would not have been achieved by simply swapping one storage system for another. As the service evolved over time, our initial design choices became less optimal, and the migration surfaced opportunities to rethink them. The gains came from focusing on optimization opportunities, redesigning the data model, and cleanly separating storage concerns. Through shadow reads and writes, followed by a gradual rollout, we completed the migration with zero downtime and no data-integrity issues. The result is a system that fits its workload well and a foundation that makes future storage changes safer and easier to attempt.
Join us
Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
In Part 1, we introduced Palana, Grab’s Kubernetes-native secure execution platform for autonomous AI agents. We discussed the underlying need for isolated environments and covered its core design principles: treating isolation as the unit of trust, keeping credentials out of agent hands, and mediating all network access. In this second part, we’ll dive under the hood into Palana’s architecture, look at the agent lifecycle, and share the key lessons we learned from putting this system into production.
Architecture overview
The core request path looks like this:
Figure 1. Palana architecture overview.
The agent pod runs in a namespace owned by one user and one agent. It gets default-deny style network policy, domain name system (DNS), access to required platform services, and a persistent /data volume. Browser traffic enters through Traefik. LLM traffic goes to the LiteLLM wrapper in the gateway namespace. General Hypertext Transfer Protocol (HTTP) and Hypertext Transfer Protocol Secure (HTTPS) egress goes through the proxy namespace. Secrets are read from Vault only by the component authorized to use them.
The operator is responsible for turning a user request into the concrete Kubernetes shape:
The user creates an agent through pcli (Palana command-line interface) or the portal.
Palana writes a UserAgent or Agent custom resource with the raw user identity.
The operator creates the user and agent namespaces, service accounts, role bindings, storage, network policies, and ingress.
The user runs a template or container image.
Admission webhooks inject proxy environment variables and enforce pod-level restrictions.
Logs, policy decisions, and activity signals are emitted to observability systems.
Agent lifecycle
From a user’s perspective, the basic workflow is intentionally small:
Behind those commands, Palana provisions an isolated execution environment:
Namespace: agent-{sanitized-user}-{agent}
Service account: bound only to that namespace
Storage: an Amazon Elastic File System (EFS)-backed persistent volume claim (PVC) mounted at /data
Ingress: an agent-specific hostname protected by Concedo-backed browser auth
Egress: forced through platform proxies, except for approved internal platform services
Secrets: split between agent-readable and proxy-only Vault paths
Policies: proxy egress, network egress, and optional inter-agent peering rules
The same lifecycle is exposed in the portal for users who prefer a browser user interface (UI).
How Palana handles identity
Human authentication uses Concedo OpenID Connect (OIDC). pcli login performs a browser-based authorization code flow with Proof Key for Code Exchange (PKCE) and stores the resulting identity in an isolated kubeconfig. Browser access to agent UIs is protected by OAuth2-Proxy through Traefik forward auth.
The important detail is that Palana keeps the raw user identity, such as an email address, as the authoritative owner on the custom resource. That raw identity is used for Kubernetes role-based access control (RBAC) subject matching. Sanitized forms are used only where Kubernetes object names, labels, namespaces, or Vault paths require safer strings.
This split prevents a common class of identity bugs: the display-safe or path-safe version of a user ID should not accidentally become the authorization subject.
In the future, we will integrate Palana via SPIFFE (Secure Production Identity Framework for Everyone) and SPIRE (SPIFFE Runtime Environment) with the rest of our service mesh, to provide an agentic identity — a combination of user and agent instance id — that can then be controlled as a subset of a user’s capabilities. This gives us a first step into “agents on behalf of users” with cut-down permissions while the wider industry firms up the approaches via Open Authorization (OAuth) and other controls.
How Palana handles secrets
Palana’s Vault layout is designed around least privilege:
The first path is for secrets the agent is allowed to read through its per-agent Vault role. The second path is for credentials the agent can use only through the proxy. For each proxy-only secret, Palana can create an agent-visible placeholder value. The placeholder is inert unless the request goes through the approved proxy path.
This gives teams a practical migration path. Existing clients can often be configured with a token-looking value, while Palana keeps the real token out of the runtime.
How Palana handles LLM access
LLM calls go through litellm-proxy-wrapper, which sits in front of LiteLLM and GrabGPT. The wrapper derives agent identity from Kubernetes context rather than trusting client-provided headers. It then looks up the per-agent GrabGPT credential in Vault and forwards the request to the correct upstream route.
Provider routing and credential handling can evolve centrally.
How Palana handles network access
Network control is split into two layers.
At Layer 3 and Layer 4, Kubernetes NetworkPolicy and Cilium enforce which pods can talk to which namespaces, services, and classless inter-domain routing (CIDR) blocks. Agent namespaces are locked down to the platform paths they need: DNS, Vault, the egress proxy, the LLM gateway, and the Kubernetes application programming interface (API) patterns the platform explicitly supports.
At Layer 7, the proxy policy controls HTTP and HTTPS destinations by host, method, and agent identity. Open Policy Agent (OPA) evaluates per-agent policy. The proxy logs allow and deny decisions in structured form.
This split is deliberate. NetworkPolicy is good at containment. The proxy is good at application-aware decisions and audit. This allows us to be very expressive in the restrictions we place on our agents — by default, they get nothing; if they should have access to an internal service they get only that service, and cannot be used as an entry point to the wider internal environment.
Observability and operations
Palana treats observability as part of the safety model, not a nice-to-have. The platform emits structured logs for proxy decisions, Git activity, LLM requests, agent lifecycle, and idle-shutdown decisions. Operators can query activity by namespace, user, host, decision, or component.
One example is idle shutdown. Long-running agents are useful, but idle workloads consume cluster resources and expand the surface area that platform teams must monitor. Palana’s reaper records the most recent observable activity for each UserAgent. It combines signals from gateway/proxy logs, Git activity, Slack-routed agent messages, and Prometheus network activity. After a configurable idle threshold, it can warn the user and stop the workload while preserving /data, RBAC, namespace, and Vault state.
This is a good example of the platform philosophy: stop the compute, keep the state, and make resumption easy.
In addition, as we move into agentic operations, we use the many signals generated by Palana itself to aid our agents. For example, we have an agent that can monitor user workloads and provide advice and assistance if it spots issues — say, an agent is consistently out of memory (OOM), the ops agent can see that and message the user with instructions on how to increase the allocated memory. We don’t need to special-case every possible issue; instead we have agents that understand Palana logs and are able to communicate with the users themselves.
What we learned
Agent platforms need security controls at the platform layer
Prompt-level guardrails and model policies are useful, but they are not enough. Agents call tools, tools call services, and services use credentials. Palana puts controls where the action crosses a trust boundary: identity, egress, secrets, ingress, Git, and Kubernetes API access.
The user experience matters as much as the control
If the secure path requires every team to learn Terraform, Vault policy syntax, Kubernetes RBAC, and proxy configuration before they can try an agent, teams will work around it. Palana uses pcli, templates, and the portal to make the safe path the easy path.
Separating “can read a credential” from “can cause a credentialed request” is powerful
Proxy-only secrets are one of the highest-leverage design choices. They let agents perform authenticated work without turning the agent filesystem, logs, process environment, or prompt context into a credential store.
A namespace boundary is simple, but it compounds
Per-agent namespaces give us a consistent place to apply RBAC, storage, network policy, logging labels, resource quotas, and lifecycle controls. The pattern is easy to reason about during incidents: identify the namespace, identify the owner, inspect the policy, and isolate if needed.
Long-running agents need lifecycle management
Once agents persist for days or weeks, “run a container” becomes an incomplete product. Users need resume semantics. Operators need idle cleanup. Security teams need audit history. Platform teams need a way to rotate credentials, update images, and stop workloads externally.
What’s next
Palana is increasingly becoming a substrate for larger autonomous systems rather than only a place to run individual agents. Emerging patterns include:
Supervisor systems that route work to a pool of scoped agents.
Slack-native agents that wake up, handle a task, and scale back down.
Remote development environments backed by persistent cloud state.
Agent swarms where each worker has a separate namespace and credential scope.
Operational agents that investigate platform health and propose or apply small fixes under policy.
Security experiments around supply chain monitoring, token rotation, transport layer security (TLS) inspection, and automated isolation.
The north star is not “let every agent do anything”. It is to make useful autonomy boring to operate: attributable, inspectable, revocable, and recoverable.
Conclusion
AI agents are most valuable when they can act in real environments. That is also when they become risky. Palana gives Grab a way to keep both sides of that tradeoff in view: teams can move quickly with self-service agent environments, while the platform keeps isolation, identity, secrets, network access, and auditability as defaults.
We expect the underlying tools and models to keep changing. The platform primitives are more durable. Agents will vary, but they will still need a place to run, a way to authenticate, a boundary around their actions, and a record of what happened.
That is the role Palana is designed to play.
Join us
Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Artificial intelligence (AI) agents are moving from experiments into everyday engineering workflows. They can read code, call application programming interfaces (APIs), run tests, create merge requests, answer Slack messages, and keep long-running state. That makes them useful, but it also changes the risk model – especially as agents get more autonomous in their use of tools. An agent with network access, credentials, tools, and memory is no longer just a chat interface. It is a workload that can act.
The more capability we give to the agents, the more valuable they get – but they also get riskier, and maintaining controls and oversight gets more challenging. We need isolated environments, with clear intentional capabilities added rather than just inheriting “everything on your laptop”.
Palana is Grab’s Kubernetes-native platform for running those workloads safely. It gives each agent an isolated namespace, persistent storage, controlled ingress, proxy-mediated egress, Vault-backed credential injection, large language model (LLM) routing, Git access controls, structured audit logs, and emergency kill switches. It is currently used to run hundreds of agents, including remote development environments, Slack automation, OpenClaw workers, Hermes agents, and other long-running internal systems.
In this post, we share why we built Palana, what it does, and how its architecture lets teams experiment with autonomous agents without giving up control over identity, secrets, network access, and operational visibility.
Introduction
The first wave of AI coding tools lived close to the user: an integrated development environment (IDE) plugin, a chat window, or a command-line assistant running on a developer’s laptop. That model is familiar and easy to adopt, but it has limits. Long-running agents need persistent state. Team workflows need shared access through Slack or web user interfaces (UIs). Security teams need to inspect what an agent is doing, and apply highly granular controls over what an agent can do. Platform teams need a way to stop, resume, update, and audit the workload.
As usage grew, we started seeing the same question in different forms:
How do we let agents do useful work inside the company without treating every new agent as a bespoke infrastructure project?
The answer was not simply to “run agents in containers”. Containers help package the runtime, but they do not answer the harder platform questions:
Which user does this agent act on behalf of?
What credentials can it use?
Can it see another user’s state?
Can it connect directly to the internet?
How do we inspect LLM, Git, and Hypertext Transfer Protocol (HTTP) activity after something goes wrong?
How do we stop an agent quickly without trusting the agent to cooperate?
How do we give teams a self-service experience without handing them cluster-admin access?
Palana is our answer to those questions.
What Palana is
Palana, an in-house proprietary system built by the CyberSecurity team at Grab, is a secure execution substrate for autonomous and semi-autonomous agents. The name comes from a Sanskrit root associated with protection, maintenance, and care. That maps well to the platform’s purpose: Palana is not trying to be the agent’s brain. It is the environment that contains, observes, and sustains the agent while it works.
At a high level, Palana provides:
A Kubernetes namespace per agent, with role-based access control (RBAC), resource quotas, network policy, and storage scoped to that agent.
A command-line and portal experience for creating, running, stopping, configuring, and inspecting agents.
Persistent /data storage so long-running agents can preserve memory, caches, repositories, and session state across restarts.
Browser and shell access for interactive workloads such as Claude Code UI, OpenCode, IDEs, ttyd, or Secure Shell (SSH)-backed development flows.
LLM access through a LiteLLM wrapper that injects per-agent GrabGPT credentials from Vault.
HTTP and HTTPS egress through an Envoy and ext-authz proxy path, with Open Policy Agent (OPA) policy checks and structured request logs.
Proxy-only secrets, where agents can reference placeholder tokens but cannot read the underlying credentials directly.
Git access through a bastion path so repository operations are attributable and policy-controlled.
Kill switches and idle shutdown so the control plane can isolate or stop workloads from outside the agent process.
This combination lets Palana support several categories of work:
Secure OpenClaw and agent-framework testing.
Cloud development environments accessible from a browser or SSH client.
Fast prototyping and testing for agentic workloads in a secure environment.
Slack-connected agents such as cts-aergia and Claude-to-Slack workflows.
Long-running task agents such as Hermes, Matlock, Butler, and custom team automations.
Higher-order systems where agentic supervisors launch or route work to scoped agents.
Why we built it
The immediate need came from security research. We wanted a place to run and investigate OpenClaw and related agent frameworks without exposing the broader internal network or placing raw credentials inside the agent runtime. That use case forced us to design for containment from the beginning.
The broader need quickly became developer productivity. Once the basic primitives existed, Palana became useful for remote coding, Slack automation, internal assistants, long-lived experiments, and agentic operational workflows. Grabbers wanted agents that could keep context over days or weeks, run from corporate infrastructure, access approved internal services, and survive laptop sleep, local dependency drift, or network changes.
The security and productivity goals reinforce each other. If the safe path is self-service and ergonomic, teams are more likely to use it. If the productive path is observable and policy-controlled by default, and the appropriate security is baked into the system automatically, platform teams do not have to retrofit controls after adoption.
Design principles
Palana’s architecture follows a few principles that shaped most of the implementation.
Isolation is the unit of trust
Each agent gets its own namespace, service account, storage, network policy, and Vault scope. Agents should not see each other’s pods, secrets, or filesystem state by default. Inter-agent communication is possible, but it goes through explicit peering rules rather than ambient pod-to-pod reachability.
This means the platform does not have to assume every agent framework has perfect multi-tenant isolation internally. A framework designed as a single-user assistant can still be hosted safely by giving each user or worker its own Palana boundary.
Credentials are never given to the agent
Traditional application hosting often gives credentials to the workload as environment variables or mounted files. That is risky for agent workloads because the agent may execute tools, run untrusted code, summarize files, install packages, or expose a web UI.
Palana separates two kinds of secrets:
Agent-readable secrets live under the agent’s own Vault path and are available only to that agent’s service account.
Proxy-only secrets are stored under a separate Vault path and are read by the proxy layer, not by the agent.
For proxy-only secrets, the agent sees a placeholder such as TOKEN_GITHUB_PAT or TOKEN_GRABGPT_API_KEY. When an outbound request travels through the proxy path, the proxy replaces the placeholder header with the real credential from Vault. The remote service receives a valid token, but the agent process never stores the token in its own environment or config.
This pattern is especially important for LLMs, source control, API integrations, and browser-like tools where prompt injection or dependency compromise could otherwise expose long-lived credentials.
Egress is a control point
Agents can be useful only if they can call tools and services. Instead of forbidding network access, Palana makes network access observable and policy-mediated.
Agent pods receive proxy configuration automatically. External HTTP and HTTPS traffic flows through Envoy. Envoy asks ext-authz-proxy to identify the calling pod, evaluate policy with OPA, log the request, and optionally inject credentials. HTTPS traffic can be terminated by the proxy’s man-in-the-middle (MITM) listener for header inspection and replacement, with the generated certificate authority (CA) distributed to agent pods.
This gives the platform a place to answer questions that normal Kubernetes networking cannot answer alone:
Which agent made this request?
Which user owns that agent?
Which host and method were requested?
Was the request allowed or denied?
Which placeholder credentials were replaced?
Did the request go to an internal service, an LLM gateway, GitLab, or the public internet?
The control plane must stay outside the agent
Palana assumes an agent might become confused, compromised, or uncooperative. Operational controls therefore live outside the agent process. The operator reconciles namespaces and policies. The proxy controls egress. The portal and pcli (Palana command-line interface) manage lifecycle. The kill switch is enforced with network policy. Idle shutdown is handled by a separate reaper CronJob.
That separation matters. A kill switch that asks the agent to stop is a feature. A kill switch that removes the agent’s network path is a safety control.
Use Kubernetes primitives where they fit
Palana is intentionally Kubernetes-native. Agents are represented by custom resources. The operator reconciles namespaces, RBAC, storage, services, ingress, and network policies. Users can interact through pcli or the portal, while platform engineers can still inspect the underlying Kubernetes objects when debugging.
This gives us a layered experience: simple workflows for users, direct primitives for advanced operators, and infrastructure-as-code for the deployed platform.
Conclusion
By centering the design around isolation, controlled egress, and proxy-mediated secrets, Palana provides a secure foundation for AI agents to operate within Grab. In Part 2, we will dive deeper into the under-the-hood architecture of Palana, exploring how it orchestrates agent lifecycles, handles LLM routing, and maintains operational visibility.
Join us
Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
A few weeks ago, we published our initial findings from Project Glasswing, looking at what happens when you point frontier security models at an enterprise codebase. We also explored how our defensive structures adapt to protect our infrastructure and customers from threats posed by frontier AI. Since then, the AI ecosystem has continued to shift rapidly — developers who’ve built tightly around a single model have already experienced what happens when that model is no longer available or gets superseded by a more capable one. These market shifts only reinforce our core thesis: no matter which underlying model is leading the pack on any given day, the future of agentic workflows will not be found in standalone models, prompts, or single-agent sessions.
Moving from a localized security “skill” to a continuous, fleet-wide scanning pipeline requires an architecture where models are treated as interchangeable components. Relying on a single model inherently limits defensive coverage, as the same system will tend to look at code paths through the exact same lens. To counter this, models should be frequently interchanged and cross-tested. By varying the models across the pipeline — such as using one model for initial discovery and an entirely different one for validation — we can ensure that vulnerabilities are cross-checked by distinct sets of logic. Furthermore, a true enterprise-scale harness must look beyond isolated repositories to trace vulnerabilities across cross-repo dependencies, ultimately filtering thousands of raw candidates down to a trusted, triaged queue of actionable fixes.
This post serves as a practical look at how to build that model-agnostic layer, focusing on how we manage state controls, eliminate false positives, and coordinate end-to-end triage at scale.
Two objections, up front
The first post made the case for why generic coding agents can’t do this job. The main issue is that agents only hold one hypothesis at a time, fill their context window after covering a sliver of a real repo, and then lose information during context compaction. For more details, read that post.
Before we move forward, we would like to answer two likely questions.
“Why not use subagents instead of a harness?” Subagents are useful, and they are a good starting point. But security analysis needs hundreds of separate investigations that survive across runs, don’t share a context window, and can be re-scoped and cross-referenced later. It needs persistence, deduplication, resumability, and eventually fleet-wide dependency tracing. That’s an orchestration problem, and a prompt can’t get you there.
“Is this blog post just an ad for frontier models?” No. Our approach centers on the harness, not the model. When it comes to vulnerability discovery, we run it with whatever frontier model is currently best at what we need. When we point different models at the same target, they each turn up a different share of the bugs. The harness is the bit that lasts. If you build your own system, design it to be model-agnostic from day one. This will allow you the freedom to use any model of choice without constraints.
It all starts with a skill
We started with a ~450-line security-audit skill that we ran on a single repository, and adjusted the prompts until we surfaced real bugs. Later, we added the orchestration that became the plumbing of the entire system. The real value lives in the prompts themselves, and our prompts continue to carry the initial skill’s attacker scenarios, bug classes, and anti-pattern detections nearly unchanged.
The skill was written to run a 7-phase audit in one session:
Three parallel research agents do recon and write an architecture.md.
One Hunter agent runs per class attack, trying to break the code rather than review it.
Adversarial validators try to disprove each finding.
The survivors are written up as a human-readable vulnerability report.
They’re also emitted as findings.json against a schema, and a mechanical check validates that file.
Finally, a fresh agent independently re-verifies every finding against the source.
The surviving, re-verified findings are submitted to the ingest API.
That first skill maps almost directly onto the later harness:
Skill phase
Harness stage
Recon agents write architecture.md
Recon
Hunters run per attack class
Hunt
Validators disprove findings
Validate
Surviving findings become a report
Report
findings.json is checked mechanically for schema adherence, not correctness
Mechanical validation of line numbers and functions in findings
Fresh agent re-verifies findings
Independent validation
The skill worked, but it quickly revealed its limits. Looking at the coverage metrics, a single run finds only about half the bugs you’d catch across multiple runs. In our experience the ones it did find skewed toward the simpler and less subtle. Once your process is basically “run it ten times and diff by hand,” you probably need to start looking at a real harness.
While running and fine-tuning the skill, we ran into three walls:
Context exhaustion: An hour in, the context window fills up and the model will cannibalize its own memory, instantly forgetting the bugs it spent all morning tracking down. We broke this bottleneck by externalizing the state entirely, treating the LLM as a stateless compute engine.
Persistence: A crash mid-run means starting over. Losing hours of work to one AI rate-limit error or connection flakiness is an incredibly expensive way to realize you need a better architecture.
Cross-repo reasoning: A single repo session is completely blind to the relationships between applications that consume it, and the number of bugs that surface when you inspect the interface between components is probably more than one might expect.
ADVICE: A real but minimal harness consists of just Recon, Hunt, and Validate stages kept in a database, alongside a separate Validator that can’t file its own findings. You should skip cross-repo tracing entirely until you have more than one repository that matters. Skip a dedicated Deduplication agent until you are actively drowning in noise. Start with a skill in your development environment, get your prompts working well, and only build the next architectural stage when not having it is the specific thing slowing you down.
Codifying the skill into a pipeline
Most AI security write-ups in this space are about a single repo or a curated benchmark; running a whole fleet this way, with cross-repo tracing, isn’t something we’ve seen written up elsewhere. Our codebase spans a massive mix of languages — Rust, Go, C, Lua, TypeScript and Python, alongside various configuration management systems, static configs, and all sorts of additional context. So we had to come up with something new that worked for us. Going from that first slash-command run to a fleet scanner that could cover 128 distinct repos, automatically finding and interrogating relevant dependencies, took about six weeks. Codification was mostly mechanical: we lifted each phase of the skill into its own agent, put a database behind it and an orchestrator in front. The mapping was almost one-to-one.
The entire fleet runs on one unified harness with no per-language tuning and traces the dependencies between repos. While offloading syntax to a model makes the system language-agnostic, the differentiator is its ability to trace dependencies between repos. The harness itself doesn’t care if it’s looking at C pointers or a TypeScript file; it focuses on the higher-level logic of security orchestration. This allows us to scale across hundreds of different codebases, without having to write custom language parsing.
A two-stage vulnerability research workflow
Our entire vulnerability research workflow is built on a two-stage operational framework: the Vulnerability Discovery Harness (VDH) and the Vulnerability Validation System (VVS).
The VDH functions as our discovery engine, proactively scanning codebases to surface potential security issues. Once bugs enter the VVS, which allows multiple harnesses to feed into it, they go through stages of Deduplication, Judgment, and finally Fixing, as we’ll talk about later.
We use one model for VDH, but we use a completely different model for VVS, so the models are effectively double-checking each other. There is an obvious security benefit to this: by forcing Model B (VVS) to judge the output of Model A (VDH), you ensure that the finding is evaluated by an entirely different set of logical weights and training data — one that acts as an unbiased, adversarial third party whose sole job is to ruthlessly stress-test Model A’s assumptions. And operationally, we benefit from treating model providers like interchangeable commodities. Model providers can change temperature, caching, and inference effort budgets over time, even within one model version. Instead of building a system that depends on a model behaving predictably over time, our harness is built to absorb downstream volatility without breaking.
Stage 1: Vulnerability Discovery Harness (VDH)
The first post covered what each agent/stage is for, so we’ll talk about the parts it didn’t: the glue between stages, and the handful of details that decide whether any of it works.
Agent/stage
Primary Role
Sub-agents / Tooling
Recon
Maps out the target architecture and maps potential threat vectors
It spawns siblings (these handle between 9% and 20% of fleet-wide tasks depending on the model). It reaches out to and writes to the Wishlist tool.
Validate
Mechanically checks the finding, then adversarially disproves it
Runs in two passes: plain code handles the initial schema/path checks, then a single isolated agent tries to disprove the finding before it can be filed.
Gapfill
Generates new hunt tasks for empty coverage cells
Enqueues fresh hunt tasks for any under-tested (area × attack-class) cells that still look thin
Dedup
Identifies and consolidates overlapping findings
Combines deterministic code and agents to cluster findings by root cause, folding them together in real time
Walks the graph to add hunt tasks inside every identified consumer repo to make sure cross-repo bugs are caught
Feedback
Learns from pre-existing reports and optimizes future runs
Takes validation failures, shallow runs, and repeated misses, and instantly rewrites queued prompts to make future tasks sharper.
Report
Renders human-readable report
Just a script, no model required
Table 1: Vulnerability Discovery Harness (VDH)
Stages four through eight run as a continuous producer-consumer loop. As the initial hunt progresses, the Gapfill, Feedback and Trace agents generate new tasks; Dedup folds overlapping findings back together and the rest of the loop keeps consuming the queue. This ensures a vulnerability discovered late in the cycle is still validated, reported and checked against other code to make sure it doesn’t contain the same bug, all within the same run.
Splitting the pipeline this way guarantees strict context controls. If you fill the context window, the model starts hallucinating. We keep each agent’s job hyper-focused, keeping context usage below 25% of the total window. A naive “read all files” approach will blow past this limit every single time.
One thing that caught us out was that persistence needs to be factored in before parallelism. You do not want to throw away a five-hour run because of an unforeseen error. Every stage writes to one SQLite database keyed by (run_id, repo, stage). Any stage can resume, retry, or get pulled into a later run without redoing work. Findings are streamed and saved as they happen, so a crash costs you the task in flight and nothing else.
ADVICE: Sometimes a transient API error comes back as text in the (200 OK) response stream instead of throwing a code exception. To the orchestrator, this looks exactly like a task that finished cleanly. You must explicitly classify the response text, not just trust the exception type, or you end up logging empty runs as successes.
Dynamic threat modeling
During the Recon stage, the agent writes the threat model instead of being handed one. Beyond about ten built-in attack classes (many forms of injection, memory corruption, protocol parsing, timing side channels, and others), the Recon agent can invent repo-specific classes on the spot, each with its own methodology. It writes a custom taxonomy tailored specifically to that codebase, which is used to more tightly scope the Hunter agents.
Reading source code isn’t enough to understand how it behaves under stress, especially for subtle undefined-behavior bugs in C and other lower-level languages. The Hunter agents move past code reading and transition into active execution. They compile fragments, build small versions, and attack them. The biggest jump in quality came from giving Hunters a sandbox (built on unshare) to crash binaries.
ADVICE: If the harness itself runs inside Docker, that sandbox needs seccomp=unconfined and apparmor=unconfined or it will silently fail to start. It’s a one-line fix that saves you a day of head-scratching if you aren’t an expert in nested containerization, like us.
Micro-forks and the wishlist
Beyond the core pipeline stages, we added two specialized mechanisms that grant the Hunters significant autonomy to adapt their focus and request external resources without derailing an ongoing analysis:
Sibling Forking: This helps ensure that if a Hunter agent trips over an interesting code path that is outside the current scope, it doesn’t wander off track. It uses a tool call to fork a sibling agent with a precise structural seed. Fleet-wide, this accounts for roughly 9% of tasks, though the rate is highly model-dependent — from near-zero to about a fifth, depending on which model is hunting.
The Wishlist: When an agent needs a tool it doesn’t have, often a Validator confirming a Proof of Concept (PoC) or a Hunter wanting to build something (like a specific build environment, a VM, or some prod config files), it writes to a central wishlist. It provides enough context for the system to automatically re-run that exact task once a human provides the dependency. Some of these can be partly self-healing: if the container needs to be rebuilt with some changes, this can autonomously happen after the run by having a generic coding harness monitor the logs.
The wishlist has been written to 25,472 times across 128 repos since the wishlist was added, and it’s the main way the agents talk back to us. One that landed while we were writing this: “I need a FreeBSD VM to confirm this PoC end-to-end.“
Fleet-wide cross-repo tracing
After the initial cleanup, a Tracer agent checks how different software components are connected. It looks for a specific path: can a potential attacker send harmful input from the outside to a vulnerable part of the system? If the answer is yes, the Tracer agent automatically spawns fresh hunt tasks inside the consumer repository. To make this work, you need a unified, cross-repo symbol index and an accurate dependency graph. This allows you to uncover deep, systemic flaws that a standard single-repo scan would miss.
Running our harness across an entire fleet of repos revealed two lessons that only surfaced when this was done at scale.
First, deduplication is its own problem, big enough to need its own agents. When you are scanning a handful of repositories, you can manually eyeball overlapping bugs. Simple string matching or file-path checks won’t save you here. Determining whether two complex logic flaws are actually the exact same root bug sounds trivial, but it isn’t. It requires so much cognitive reasoning that we had to deploy dedicated Dedup agents just to clean up the noise, along with their own heuristics and ways of reducing the work.
The second is to not wire in static analysis early. We plumbed Semgrep all the way through, and the Hunters invoked it zero times in a month of runs. They would rather read and run the code. The wishlist, by contrast, was the single most-used tool in the system. It’s worth paying attention to what the agents actually reach for, rather than what you think they’ll want.
Making findings you can trust
The agent will edit the source code so its own exploit works, then triumphantly report the bug it just created. It will write a test that proves something entirely tautological like “exec() executes things, therefore critical vulnerability”. Or it builds an exploit that runs fine but proves nothing, because the threat model behind it is nonsense. If your harness doesn’t actively fight this, all you’ve built is a faster way to produce junk.
A Hunter has to state the threat model before it’s allowed to file anything. It has to define exactly who the attacker is, and what boundary the vulnerability crosses or what assumption it breaks. The output schema ordering enforces it. This requirement eliminates the vacuous findings, the “if a user has database write access, they can write to the database” kind.
Every confirmed finding ships with a PoC written as a test that runs against the original, untouched codebase. This prevents the agent from editing the source files to force an exploit to land. If there is no working PoC, we treat the finding as fake. In practice, that’s a Hunter compiling a thirty-line parsing loop, running it with memory protection enabled, and demonstrating that the incorrect read stride is originating from a stack address rather than the expected message body. You can re-run it yourself. Furthermore, every confirmed finding must also ship a proposed patch. What actually reaches our review queue is a verified bug, a working test, and a functional git diff, not just a vague text description of a problem.
Before an exploit path survives, deterministic code (written in plain code, not another model) mechanically verifies that the cited files and paths actually exist, and confirms that both the patch and the test parse correctly. This Validator cannot log findings of its own; its sole job is to aggressively disprove the Hunter‘s theory. If a Hunter is allowed to grade its own homework, it will confidently validate everything it outputs.
We don’t claim a false-negative rate for our system. There’s no labeled set of every real bug in a codebase, so any claimed recall number is entirely speculative. What we can watch is whether re-runs keep turning up new bugs (they do) and whether coverage is still growing across runs. It’s all a proxy, as you don’t know for sure how many bugs exist in a single codebase, but it’s a good-enough way of measuring effectiveness.
Stage 2: Vulnerability Validation System (VVS)
A finding coming out of the harness is just the start of the triage process, with all discoveries landing in a single, shared VVS that currently holds 13,841 findings across 145 repos in total. Triaging that volume is its own massive engineering problem, and it matters just as much as the hunting. That triage engine runs on a different model from the harness, broken down into three distinct jobs.
Agent/stage
Primary role
Spawns/ sub-agents/tooling
Dedup
Identifies if a vulnerability is already in the system, or raised as internal Jira ticket already
Deterministic: plain code builds inverted indexes over files, functions, trust boundaries, and rare tokens, then hands each finding a short candidate list
Probabilistic:Dedup agent reasons over that short list, Stable cross-run key reopens existing records
Judgment
Production reachability and validation
Single agent — builds context about the bug from MCP servers, to get the shape of what the service looks like in production. Searches the wiki, Jira, git, config, and all available other sources to try and understand whether a bug is truly applicable to our production environment, and then score the vulnerability against this. It also validates the bug against source code to understand if the bug still exists on the latest main branch.
Fixing
Generates patches, runs regression tests
Runs the regression test before and after (filtered to the affected test; full suite only when per-test filtering isn’t available). It requires a clean fail→pass flip on the target test to clear the gate. If the post-patch test fails, or if a global run detects downstream regressions, the commit is automatically blocked and flagged for human intervention.
Table 2: Vulnerability Validation System (VVS)
Deduping
Comparing every single finding against every other finding using an LLM scales at O(N^2), which falls apart completely at scale. To keep the model off the critical path, deterministic code builds inverted indexes over the structured data (touched files/functions, trust boundary, rare tokens) to generate a short list of real candidates. Only then does an agent look at that short list to see if a single fix would close several of them. Stable cross-run keys ensure re-found bugs reopen existing records rather than spawning new ones.
Contextual judgment
Judgment is a second, independent pass over what survived. The agent rechecks the latest information, pulling from deployment, environment, and config context to determine if the code path is reachable in prod, and identify the repo owner. This process filters “exploitable now” from “real but latent” and from “real but filed against the wrong component.” It’s moving a pile of chaotic findings into a risk-driven orchestration workflow.
Automated fixing
The Fixer takes the proposed patch and unit tests, rewrites them to match the repo’s style, applies the diff, and runs targeted tests. A clean fail→pass flip is the ideal and the only auto-cleanup case; a failing post-patch test blocks the commit. The Fixer never merges code on its own; a human must review the branch. This gate is the non-negotiable, human-in-the-loop safeguard that enables a clean, unbreakable cryptographic trail for change management compliance. Left to patch freely, a model will happily fix a security bug while quietly breaking an unrelated feature or adding dozens of new bugs.
Across all three triage jobs, each agent is confined to one narrow task wrapped in deterministic bookkeeping code, and nothing writes to production without a human signing off on a dry run. While this pipeline moves the engineering bottleneck from finding bugs to reviewing and landing fixes, the Fixer remains the youngest and slowest part of the system.
What it costs
Running hundreds of agents over a fleet of repos is not cheap, but at least the shape of the spend is predictable. Almost all of the compute budget goes directly into the hunt stage. This makes Gapfill our cost-to-coverage lever, as each additional pass costs roughly half as much as the initial hunt.
Because the cost per repository varies wildly, we budget per repo rather than per run. We enforce a strict task cap per repository and spin up a worker pool of anywhere from 50 to 200 workers. That way you can spend money on the repos that are actually finding things, and not waste it on the ones that aren’t.
It’s also why, for us, the big scans are a periodic backlog sweep and not a per-PR check. A full scan of a complex repo can take hours; the worst run took just over 14 hours. Cheaper, smaller harnesses are the right tool for that job.
How we tell it’s working
We measure our system’s effectiveness by tracking how efficiently our automated pipeline filters deliberate engineering noise into high-quality, actionable findings. Because we intentionally tune our Hunters to over-report subtle primitives that could be chained into larger attacks, our true indicator of success is how sharply we can refine that initial mountain of raw data, before it ever reaches a human.
To gauge this, we track exactly how many raw findings survive each validation stage over time. Thanks to better context injection from our Recon phase, our initial validation rejection rate dropped from 40% down to 11%, while the share of high-integrity findings climbed from 35% to 58% (representing ~12,057 lifetime findings).
Here’s the lifetime breakdown from raw candidates to actionable findings, at the point in time this blog post was written.
Vulnerability Discovery Harness (VDH)
Raw candidates: Everything the discovery harness emitted before independent validation.
Needs repro: Findings that appeared plausible but required manual reproduction before being trusted.
Rejected at validation: The validator disproved the threat model, exploit path, affected code, or evidence.
Duplicates: Candidates collapsed onto another finding from the same harness.
Survived validation: Findings that passed the independent validation gate and moved into the VVS.
Bugs that went elsewhere: Findings deliberately routed outside this flow.
Vulnerability Validation System (VVS)
Another vulnerability harness: Other automated sources feeding the same validation system.
Total bugs in system: The combined pool after ingest.
Duplicates: Findings the dedup pass identified as already covered by another canonical finding or ticket.
Wrong repo / other / not a risk: The noise bucket: misattributed findings, defense-in-depth, or latent risks.
Bugs sent to teams: Finalized, clean findings ready for remediation.
Judged Internet-exploitable: High-urgency findings a realistic attacker could trigger in production.
Not judged Internet-exploitable: Lower-urgency, actionable bugs (production issues, dependency risks, or config errors).
Final severity split: The categorization used to assign priority for the engineering teams.
The core metric of the harness isn’t a speculative recall score — it’s keeping the number of unconfirmed findings in front of real humans as close to zero as possible. The architecture needs to be a relentless filtering funnel.
Out of 20,799 raw candidates generated by VDH, only about 12,057 survived validation.
When these were pushed into the VVS, joining findings from another harness, the central pool was brought to 13,841.
The Dedup agent folded away 5,442 findings as duplicates.
1,154 were routed to the queue as ‘wrong-repo’ or ‘low-risk’ and were recycled back into the system where appropriate.
Ultimately this left 7,245 actionable findings for engineering teams to act on.
Traditional compliance rules dictate arbitrary remediation windows based entirely on a static CVSS score (e.g., “Fix all Highs in 30 days”). Our contextual judgment layer turns this compliance checkbox into actual risk management.
The architecture is capable of tracking findings back to their origin, meaning that fixing a single root cause resolves an entire cluster of findings rather than just patching individual issues. VDH system performance is also measured by dividing repos into (area x attack-class) cells and running the Gapfill agent iteratively until it stops producing findings. Whenever we update an underlying prompt, we test it against a held-out repository to see if that total coverage cell number actually moves.
The harness wires automated health signals to catch system failures early in the pipeline. If a hunt finished suspiciously fast and fails to spawn sub-hunts or gap tasks, it usually indicates a crashed dependency rather than a clean codebase. To remedy this, the system flags any Hunter agent that finishes with zero findings as “shallow” and immediately requeues it for a new run.
Finally, our system’s robustness is reinforced by the independent triage pass described earlier. By re-judging all submissions with a different model and separate logical weights, we ensure an unbiased, adversarial verification that is decoupled from the specific model used for discovery, providing a trust layer that persists regardless of which model is in use.
None of this is finished. We change our system constantly, and it is nowhere near a perfect science. But raw candidate findings are cheap now, and the only work worth doing is turning them into sound, verifiable code fixes.
Building your own harness means accepting that AI models are volatile, but your orchestration layer doesn’t have to be. By decoupling your security logic from any single provider, forcing adversarial verification, and automating your triage pipeline, you can turn a mountain of LLM noise into a reliable, fleet-wide defense engine.
Every codebase is a little different, so to show you how this actually works in the real world, we mapped out a realistic benchmark based on a standard repo run. Keep in mind that this represents a single pass on one repo; over time, as the continuous fleet-wide loop deduplicates, filters, and recycles findings, it reduces the volume of lifetime candidates by roughly 65%.
Engineering hours saved via automated patching: Rather than focusing on static baselines, we measure the health of our pipeline by its technical throughput, processing velocity, and its ability to eliminate the manual triage bottleneck:
Initial Validation Cut: For a standard repository (~30k lines of code), this yields 100 initial findings, with a full run taking 3-4 hours, maintaining a hyperfocused context window throughout.
Compression: The Deduplication and Contextual Judgment Layers process these candidates in parallel. Within 3 hours, the system compresses and refines the batch of findings from ~100 raw candidates to 80 distinct, high-fidelity bugs.
Remediation: The automated Fixer processes these 80 distinct bugs at an average rate of 5 minutes per bug. In total, the system can discover, validate, deduplicate, and open functional pull requests in approximately 14 hours.
Shrinking mean-time-to-resolve for critical flaws: Of course, you can’t dump 80 patches into production all at once without breaking things. To keep deployments safe, our system uses a tiered rollout:
Critical Exposure Containment: The system isolates the critical, high, and exploitable bugs (avg. 10 out of 80). We fast-track these for a human review and introduce them into release cycles, getting them fully patched in production in 5 days.
Incremental Hardening: The remaining latent risks, minor config anomalies, and lower-urgency bugs are incrementally rolled into prod over a 15-20 day window to guarantee platform stability.
How we’re handling all of this patching
These findings are the result of an isolated, ring-fenced research experiment designed to stress-test our code. They do not represent active, unpatched vulnerabilities in our live production environment.
Because the harness runs constantly in our test environments, these specific numbers are completely out of date by the time you’re reading this. Every single bug surfaced by the pipeline came attached to a working test case to demonstrate the bug and a draft patch. Our security teams are systematically processing the reports and applying the necessary fixes, meaning the Cloudflare products you use every day are already actively hardened against these vectors.
Along with this blog post, we’re releasing the initial skill we used to develop the harness, it’s been slightly cleaned up before release so it’s easier to understand and integrate, but the skill itself remains substantially the same. Hopefully the harness itself will follow shortly. This could be a starting point for your own vulnerability harness, your own skill, or whatever suits your needs best: github.com/cloudflare/security-audit-skill
If your team is working on the same problems and would like to compare notes, reach out to us at [email protected].
Security Insights provides actionable security recommendations for every Cloudflare account. To find these insights, we perform regular scans for all accounts, zones, and DNS records, looking for potential security risks and misconfigurations.
However, two key issues emerged. First, our scans were too infrequent. Scans were only being performed every week or two, and therefore newly introduced security risks could remain undetected for up to two weeks. Second, automatic scanning was opt-in for many free plan accounts – meaning lots of accounts weren’t being scanned at all.
The risks of infrequent or nonexistent scans are rising: as automated attacks accelerate, the window for detecting security misconfigurations is shrinking. Making sure that we’re finding these issues for all of our customers is crucial to our aim of building a better Internet for everyone.
We calculated that to increase our scanning frequencies and enable automatic scanning for all accounts, we would need to increase our scanning throughput by around 10x on average – from 10 scans per second to 100 per second. But our system was already struggling with its load: millions of events were filling up our backlog waiting to be processed; our API was frequently timing out; our processes were crashing. We needed to fix our system, and we needed to make it scale.
This is the story of how we increased scanning throughput for Security Insights by more than 10x, enabled security insights for millions of customers, and doubled our scanning frequency for all customers. Read on to find out how we achieved these improvements.
How we scan for security insights
At a high level, our automatic security scans are triggered by a scheduler. When an account or zone is due for a scan, the scheduler publishes a message (or messages) to Apache Kafka, an open-source distributed event streaming platform. These messages fan out to a number of checkers: specialized Go microservices that scan specific assets or configurations.
For every message, each checker sends its results (the security insights that it found) to our internal API, which then persists these in a Postgres database.
Making it scale
Scaling Kafka
Apache Kafka is not strictly a queue: it is a partitioned event stream (though recently gained queue semantics). Within a partition, messages must be consumed and processed in order. This differs from typical queues where messages may be consumed in order but are processed out-of-order. As a result, we can only have one active consumer per partition within a consumer group.
This has two consequences for us:
Messages that are slow to process block the consumer from progressing to the next message
For each checker, we can only have as many consumers as there are partitions (each checker has its own consumer group)
We could have tried to scale by adding more partitions. However, this would have increased resource usage for the Kafka broker itself, which is shared by many other services. We reserved this as a last resort, aiming to improve our code and architecture first.
Introducing parallel processing
Although we can only consume messages in order, there is nothing stopping us from consuming multiple messages at once.
We changed our checkers to consume messages in batches, processing each message in a separate goroutine. The trade-offs are that we’d have more work to re-do if our process crashed midway through a batch, and our memory usage would be slightly increased. In our case, these were both acceptable.
Avoiding head-of-line blocking
Some messages processed by a few of our checkers take much longer to process than others. For example, one account/zone may have far more assets than another. In the worst case, these messages can take minutes or hours to process compared to the average case of seconds or milliseconds.
We opted for a very simple approach: splitting our consumer groups and checkers in two – the ‘slow lane’ and the ‘fast lane’. We could determine quickly whether a message would be slow or fast to process. If the ‘fast lane’ checker encounters a slow message, it skips it.
This solved the problem: slow messages had the dedicated resources and time to be processed with minimal delay, and fast messages were able to proceed at their regular fast pace.
Optimizing our database queries
Every insight we find gets written to our Postgres database. This is handled by a single API endpoint that our checkers invoke with a list of insights. The implementation looked like this:
for _, issue := range issues {
	_, err = tx.Exec(ctx, `INSERT INTO table ... VALUES ($1, $2, ...) ON CONFLICT DO UPDATE ...`, ...)
	if err != nil {
		return err
	}
}
The astute reader will notice that for large sets of insights, this code makes a round trip to the database per insight. With a maximum observed size of 500,000, this was half a million round trips, queries, and transactions in a single API call.
We initially tried the gold standard for bulk inserts in Postgres: COPY into a temporary table. However, we found that this approach led to bloat in the Postgres system tables.
We settled on a hybrid approach:
Using UNNEST when the number of issues was below a threshold
Using COPY when the number of issues exceeded this threshold
This provided the best of both worlds: reasonably fast inserts for huge sets of insights (seconds), and even faster inserts (milliseconds) for small sets of insights.
Investigating our API timeouts
We noticed several strange behaviours in our internal API as we tried to scale:
A large number of requests were triggering client-side timeouts
Many checkers were spending 20-90% of their processing time on a single API call
When triggering a large volume of scans, our throughput would start high and deteriorate
All of these problems had the same root cause: latency.
Our primary database is located in Portland, Oregon. Our API, however, was running active-active in both Portland and Amsterdam. Even at the speed of light, the round-trip latency between Portland and Amsterdam would be 50 milliseconds.
As a result of this latency, database queries from the Amsterdam API instance took much longer, holding connections from our client-side connection pool open. With the large volume of requests that we were making to the API, the connection pool was quickly becoming exhausted, leading to timeouts waiting for a free connection. Our average API call completed in 10 ms in Portland, but almost 3 seconds in Amsterdam!
But why the drop in message throughput? Each checker process gets assigned a set of partitions of the Kafka stream to consume. Our API is load-balanced. Since we hold the connection open throughout the life of the process, some processes had a connection to the Amsterdam API, and others had a connection to the Portland API. The partitions linked to Portland were processed quickly, but the ones consumed by the Amsterdam-bound processes were lagging behind:
Kafka lag (number of messages waiting to be processed within a single consumer group) by partition for one of our checkers. Note that we have 30 partitions in this case. Exactly 15 partitions can be seen lagging behind (the lines that reach or approach zero later than around 03/10 03:00). This is because the load balancer splits traffic evenly between our API endpoints.
This was a simple fix: we switched our API to active-passive, ensuring the active API followed our primary database. Our latency problems disappeared overnight.
Rethinking the scheduler
We’d scaled Kafka. We’d optimised our database queries. We’d fixed our API. However, we still had a problem: we needed to be sure our scans would be roughly uniformly distributed in time. It wasn’t feasible to queue all of our scans at the same time, as our Kafka topic uses a time-based retention policy: the scans would pile up in Kafka, and eventually be deleted before they could be processed.
Our scheduler was not good at uniformly distributing our scans. The number of scans that would be triggered at a given time was spiky and unpredictable. At certain points throughout the week, hundreds of thousands of scans would be triggered within minutes of each other. What was going on?
The scheduler triggers scans on fixed recurring periods. In pseudocode, the scheduler looked like this:
Loop forever:
    Find accounts where last_scheduled_at + scanning frequency <= now
    For each account:
        Trigger scan for account
        Trigger scan for all zones in the account
        Update last_scheduled_at = now
We quickly noticed that last_scheduled_at was similar for a large number of accounts in our database, which was responsible for some of this unevenness.
However, even with perfectly even distribution, increasing our scanning frequency would have compounded this problem. For example, changing the scanning frequency from every 15 days to every seven days would mean 53% of accounts would suddenly be due for a scan.
There was a further problem with this logic. Some accounts have a very large number of zones. When these accounts were scheduled, there was a cascade of scans for all of their zones. This was saturating our Kafka partitions and leading to delays for scans of much smaller accounts.
To fix these problems, we made three key changes:
Schedule zones independently of accounts: each zone gets its own last_scheduled_at field.
Randomize the last_scheduled_at time for existing accounts and zones.
Introduce adaptive rate limiting for scan scheduling.
Scheduling zones independently was an obvious way to solve the problem of large accounts. Randomizing the last_scheduled_at time (and ensuring that no scans were delayed during this process) allowed us to fix the existing unevenness in our database.
Adaptive rate limiting is slightly more interesting. Rate limiting would allow us to solve the problem of a spike in scans when we change scanning frequencies. For example, if we wanted to increase our scanning frequency to every 7 days, and we had 50 million accounts, then a rate limit of ~83 scans/second would ensure that they were spread out evenly across 7 days.
But what if we added 10 million more accounts? Then, this rate limit would force us to take 8 days to scan all of these accounts. This is where the adaptive part comes in: the rate limit is asynchronously recalculated every half-hour based on the total number of accounts and zones we have, and our scanning frequencies. This ensures we continue scanning on time even if we onboard thousands or millions more accounts and zones.
func computeRate(free, pro, biz, ent int64) rate.Limit {
   r := float64(free)/freeScanInterval.Seconds() +
      float64(pro)/proScanInterval.Seconds() +
      float64(biz)/bizScanInterval.Seconds() +
      float64(ent)/entScanInterval.Seconds()


   // Guard against zero counts. We always want to schedule at least one scan per second.
   if r < 1 {
      r = 1
   }


   // Increase rate limit beyond the 'perfect' value, to have a buffer in case of any downtime
   // or spikes in load.
   r *= rateLimitBufferFactor


   return rate.Limit(r)
}
Where we stand today
With these fixes, our 7-day moving average throughput per checker over time rose by more than 10x.
Before these improvements, we were executing around 10 scans per second. The gap between this and our target throughput of 100 scans per second seemed vast. We discussed throwing more resources at the problem, throwing more partitions at our Kafka topic – even throwing out our entire architecture.
But our fixes made all the difference. Today, Security Insights sustains over 120 scans per second during peak scheduling, exceeding our 10x improvement goal. Our internal API is no longer timing out, and our Kafka lag metrics look much healthier. These scalability improvements have allowed us to turn on automatic scanning for all free accounts and zones and increase the scanning frequency for all customers:
Free: every 7 days
Pro and Business: every 3 days
Enterprise: daily
The improved system stability has given us confidence to build new features that we were previously constrained from creating. We’ve added the ability to perform granular on-demand scans. You can now manually re-scan a Cloudflare account, zone, insight, or insight type.
Starting a granular on-demand scan from the Security Overview page in the Cloudflare dashboard
The lesson we learned is that it’s crucial to deeply understand the existing system before throwing anything away. By looking closely at our code, SQL queries, logs, and metrics (especially metrics!), we were able to increase our capacity without simply adding more pods or partitions. By questioning our assumptions, digging into weird-looking metrics, and refusing to take the easy shortcuts (such as increasing API client-side timeouts), we built a more stable and resilient system.
Throwing more resources at the problem might sometimes be the answer, but at Cloudflare, we believe in engineering our way out of problems.
Security Insights scans are enabled by default on all Cloudflare plans. Log in to the Cloudflare dashboard today to review and manage your security insights.
Grab is migrating from heavy base images like Ubuntu to Distroless images to reduce security risks. By stripping containers down to the bare application and its runtime, we eliminate unnecessary binaries and Common Vulnerabilities and Exposures (CVEs).
This migration is more than a compliance mandate; it is a strategic security decision to build a more resilient and defensible production environment. By moving to Distroless, we are fundamentally shrinking our attack surface; eliminating the binaries and shells that attackers use for lateral movement. With over 900 services already transitioned, we are on track for 80% adoption by mid-2026.
Why Distroless requires rigorous testing
Distroless adoption risk: runtime failure
However, shifting to Distroless images introduces a critical technical risk: runtime failure. A service might build perfectly in Continuous Integration (CI), but fail at the deployment stage due to:
Missing shared objects: Binaries might require specific libraries (.so files) present in Ubuntu but absent in Distroless.
Implicit links: Third-party tools may expect specific system utilities or directory structures.
Testing is required to ensure two things:
The service spins up with the correct config.
All runtime dependencies remain intact.
Scaling this verification across thousands of services manually? That would take years unless we found a way to automate the trust.
The testing methodology
As we perform changes to the Dockerfile definition of our services, it is crucial for us to include the corresponding test strategy so that changes we make do not introduce regressions in our running services. Assessing the change introduced to our services, the lowest possible testing boundary would be that of what we define as Medium Tests in Grab.
Medium tests in Grab
At Grab, we categorize our test suites into three main sizes: small, medium and large. Small tests refer to functional tests whereby mocks are introduced via dependency injection. Large tests refer to end-to-end tests that run on actual services in our staging environment where nothing is mocked.
Figure 1. Architecture diagram of a medium test environment.
Medium tests belong in the middle ground, whereby external dependencies (such as service to service dependencies) are mocked with a network proxy layer in a similar concept as WireMock, but internal dependencies like MySQL are not mocked and instead spun up using Testcontainers. In this setup, systems under test are actually built into Docker containers and run in Docker before their endpoints are being hit by test inputs, with the corresponding responses being asserted on. As such, we could now effectively test if any changes of the Dockerfile definition broke the service. An added bonus is that all of these could occur within the CI environment, without reaching the Continuous Deployment (CD) stage.
Figure 2. Happy path for Distroless changes.
This makes Medium Test effective and efficient for testing changes to the services associated with distroless adoption. We could now largely scale up our adoption process by:
Raising batch Merge Requests to dockerfile definitions for Distroless adoption.
Running medium tests in CI.
Upon passing the medium tests, automatically merge the changes and trigger CD.
Introduction of toil
The approach above works nicely for services that already have Medium Tests defined. However, we quickly hit a blocker running this rollout methodology for services without a Medium Test setup. Inherently, scaffolding Medium Tests for a service is a tedious task. Most of the toil comes from first figuring out the internal dependencies, then spinning up their corresponding test containers in test time before wiring the internal dependencies up with the service under test by updating the test environment configurations.
Figure 3. Services without Medium Test setup blocked the rollout.
These tasks are not challenging but are generally tedious to set up. At the same time, they cannot be automated completely given the different internal dependency combinations that each service uses, as well as the difference in how the configurations are being defined and used in each service. With ~400 services in scope without Medium Test setup, this became a huge blocker for our distroless migration campaign.
The need for flexibility in how each task is executed, together with each task’s fairly low complexity, made artificial intelligence (AI) a natural tool to accelerate distroless adoption work.
AI: The toil buster
Figure 4. Solution overview: AI-driven workflow for Medium Test scaffolding and migration.
AI was a good fit because the work we needed to automate had clearly defined output, and we could tell, deterministically, whether it worked. Success was straightforward: the CI pipeline would turn green, running basic Medium test health checks. With a measurable end goal and a reliable success signal, we pursued an agentic workflow rather than a one-off generation attempt.
The starting point
We started by adopting skills to guide the agent on how to proceed with Medium test work and how to unblock itself when it hit repo-specific friction. These skills gave context for scaffolding basic Medium tests, setting up internal dependencies, and debugging issues in the code. Once those foundations were in place, we rolled the approach out to a batch of 20 services, completed by the AI in about two working days. That batch validated the core hypothesis: the AI could scaffold Medium tests first, then use those tests to verify that our Dockerfile change (building distroless images) introduced no regressions.
Teaching an agent to test
At that point, the real shift was turning “can do the task” into “can repeat the behavior.” We captured the Medium-test knowledge as a list of skills grounded in Grab’s internal Medium test SDK.
Then DevSecOps wrapped those skills into an Entrypoint Skill, an orchestrator that runs a multi-phase workflow across services. The result is a single agent loop that moves from candidate detection, to scaffolding, to fixing failures, and onward to CI verification without treating each service as a brand-new, one-off problem.
Figure 5. Workflow overview for Medium Test generation.
Leveraging the skills we’ve acquired, we utilized Claude Code, Anthropic’s agentic coding tool. This tool operates by accepting a list of services and then processing them in a batch.
Detect: Is this a deployable service or is it a library? Is it still maintained? The agent skips anything that doesn’t qualify, so human time is only spent on real candidates.
Scaffold: Using Grab’s scaffolding tool, the agent generates the medium test boilerplate.
Fix: The scaffold rarely works on the first try due to the unique setup of each repository like missing environment variables, database dependencies at startup, port mismatches, and similar issues. The agent reviews its knowledge base and pattern-matches errors against known fixes.
Raise MR: Once the medium test passes locally, the agent creates a draft merge request on GitLab with a description explaining what changes were done for that specific service and why.
Monitor CI: The agent polls the pipeline, reads job logs on failure, and attempts CI-specific fixes. If the same error persists after two attempts, it flags the issue for human review.
Repeat: Push the fix and move to the next service while the pipeline runs. The agent doesn’t sit idle waiting for CI! It starts scaffolding the next service asynchronously, checking back on previous pipelines as results come in.
What made it work
Getting the workflow to function was the easy part. Getting it to function reliably across hundreds of services required deliberate design choices.
Model Context Protocol (MCP): The agent never leaves Claude Code. GitLab interactions like creating branches, raising MRs, reading pipeline error logs, all happen through a MCP server. When the agent needs Grab-specific context like what a service does, or who owns it, it queries Glean, an enterprise search tool used by Grab through its MCP integration rather than guessing. For code-level context, finding how a service is structured or how dependencies are wired across repositories, it queries Sourcegraph through its own MCP integration.
Guardrails over autonomy: The agent can only touch test files and CI configs. Application code is off-limits, enforced before every commit. It can’t gut tests to make them pass. If it can’t fix the problem, it escalates.
Knowledge that compounds: We maintain a feedback loop for scaffolding, mocking, and known failure patterns. After each batch, we review what the agent hit and promote recurring fixes into the skill. The agent improves not because the model gets better, but because its instructions do.
Integrating scripts with skills: For deterministic tasks like boilerplate generation, scripts are far more reliable than raw AI logic. By integrating these scripts as “skills,” we also optimize the agent’s performance in context window management. During test execution, standard output often produces hundreds of lines of repetitive logs that could exhaust token limits or distract the model. Using a script as an intermediary allows us to programmatically filter logs, extracting only the specific error messages or stack traces required for debugging. This ensures the AI receives a clean, actionable summary rather than being overwhelmed by noisy data.
Token efficiency: Batch runs across dozens of services burn through tokens fast. We configured a compressed communication style that cuts output by ~75%, keeping technical substance while stripping filler. Proper communication is reserved for MR descriptions and messages to service owners.
Isolated execution: Each batch run spawns the agent in its own context window. Long sessions processing dozens of services don’t bloat the main conversation, keeping the agent focused and responsive.
Human-in-the-loop: Every MR is raised as a draft; a human reviews before anything merges. A human also decides which learnings become permanent knowledge. The agent proposes; people approve.
From tests to migration at scale
With medium tests in place across our service fleet, we had the safety net we needed. The next step was automating the distroless migration itself.
The patch-test-compare loop
Figure 6. Patch–test–compare loop: baseline Medium Tests, apply Distroless Dockerfile changes, re-run tests, and triage results.
Before touching a single Dockerfile, the system runs the service’s existing medium tests to establish a baseline. Pre-existing test failures are baselined, allowing for a clear distinction between legacy issues and new regressions introduced by the distroless patch.
Then comes the distroless patching. The system inspects each service’s Dockerfile for OS-level package dependencies by scanning for apt-get install lines and filtering out packages already included in the distroless base image. Two scenarios to consider here:
If no extra packages are needed, it’s a straightforward base image swap.
If packages are detected, the system generates a multi-stage build: a builder stage installs the required packages, then copies only the necessary shared libraries into the distroless runtime stage. The result is a minimal image that still has everything the service needs to run.
After patching, the same medium tests run again. Results fall into clear categories: pass (tests still green – safe to migrate), regression (tests broke – the patch caused a problem), or already failing (was broken before we touched it). Regressions trigger an automated remediation step. A separate AI agent inspects the container for missing shared libraries and attempts to fix the Dockerfile. If it can’t resolve the issue, the service is flagged for human review.
Scaling with batch changes
The previous section explains the patch-test-compare loop, but how can we scale to handle more than one service at a time? To migrate at scale, we use batch change tooling that applies the Dockerfile transformation across dozens of repositories simultaneously, creating merge requests automatically. The system handles both standalone GitLab repositories and Grab’s shared Go monorepo, adapting the patching and MR strategy to each.
Impact on our services
Medium test generation at scale
With medium tests in place, services with possible regressions have higher chances of being caught before reaching staging, providing the safety guarantee we needed. Each generated test also became a permanent safety net for the service, not just for the distroless migration but for all future changes. Over 1.5 months, the agent raised 100+ medium test MRs across repositories, bringing more services into compliance with Grab’s “shift-left” testing initiative.
Distroless adoption
The campaign moved the needle significantly across our service fleet. Overall distroless adoption for our scope grew from 52.7% in December 2025 to 70.8% by April 2026, covering 997 out of 1,408 services.
Autonomous with oversight
The agent autonomously handles the majority of medium test generation and Dockerfile migration work with little human intervention for standard cases. Engineers remain in the loop, reviewing every draft MR and making the final call on what merges.
Engineering bandwidth reclaimed
Manually generating a basic medium test requires familiarity with Grab’s internal SDK, typically 1–3 days per repository for developers new to the framework. Across ~400 services without medium tests, that adds up to 400–1,200 engineer-days. By leveraging AI we brought this down to roughly 0.1 days per service, compressing what would have taken well over a year into a fraction of the calendar time. This freed the team to focus on higher-leverage work like improving migration tooling, handling edge cases, and advancing the roadmap beyond distroless.
Conclusion
With distroless images and stronger medium test coverage, we made Grab’s services more secure and easier to verify. We demonstrated that AI can shoulder much of the scale-up effort.
Join us
Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Cloudflare’s core is the centralized data centers that run our control plane, billing, and analytics — distinct from the globally distributed edge that handles user traffic. Core servers are bare metal, and when issues happen during reboot, the consequences can cascade fast.
Their boot sequence is orchestrated by UEFI, the modern firmware standard that initializes hardware and hands off control to the operating system. Small quirks in that handoff can have outsized consequences.
After a routine firmware update, some of our core servers were taking four hours to come back online, rather than just minutes as they did before. What should have been a one-day fleet-wide rollout was stretching into multi-day slogs. New nodes faced the full timeout gauntlet on their very first boot. Maintenance windows ballooned. Engineering teams had to babysit upgrades that should have run unattended.
This issue affected the entire Gen12 fleet — nearly 2,000 units. Every unexpected failure mid-upgrade meant restarting the entire cycle, and new capacity sat idle waiting for the timeout gauntlet to clear.
This is the story of how we tracked the cause to a firmware quirk and an over-eager linear search through every available network boot interface, and how we cut total boot and upgrade time from hours back down to minutes. Along the way, we’ll share what we learned about UEFI internals, vendor-specific quirks, and the automation strategies that ultimately solved the problem.
The network boot interface
A network boot interface allows a server to boot its operating system over the network instead of from local storage. This is critical for centralized, automated, and scalable control over how machines start up, especially across a globally distributed fleet serving different workloads. Since our servers are located in different environments and serve different purposes, they have different requirements for a specific network boot interface. The two primary interfaces are the Preboot Execution Environment (PXE) and Unified Extensible Firmware Interface (UEFI) HTTPS boot.
As part of our reboot process, our servers usually go through PXE for various automation reasons. At Cloudflare, we use the open-source iPXE, an open-source network boot firmware that supports modern protocols like HTTP and HTTPS. This allows computers to boot operating systems directly from web servers, the cloud, or enterprise storage networks with significantly faster speeds and greater reliability.
For organizations, iPXE turns the boot process into a programmable workflow. It offers advanced scripting capabilities that allow IT teams to automate complex deployments, such as provisioning servers based on specific hardware configurations or managing secure, diskless workstations.
Some of our hardware supports HTTPS-based UEFI network boot, which enables the computer’s motherboard firmware to natively download operating system files securely.
The linear search
Our tale begins with that fateful firmware update. Following the update, the first reports came through our internal channels: servers weren’t coming back online. Monitoring dashboards showed machines stuck in a pre-OS state for far longer than expected. Our initial suspicion was a firmware regression: perhaps the update itself had introduced a bug that was hanging the boot process.
To rule that out, we pulled up the serial console on an affected machine and watched a boot cycle in real time. The firmware Power On Self Test (POST) completed normally and hardware initialization looked healthy. But then, instead of quickly reaching the network boot stage and pulling down an OS image, the server sat waiting. And waiting.
The console output told the story: the system was attempting an IPv4 HTTPS network boot, timing out after several minutes, then trying IPv4 iPXE, timing out again, then repeating both — all before finally reaching the IPv6 HTTPS boot interface that would actually succeed.
Every failed network boot attempt burned roughly five minutes waiting for a timeout response. With four attempts stacking up before the correct interface was reached, a single boot cycle wasted around twenty minutes. For a routine reboot, that’s painful. For firmware upgrade automation, which requires multiple sequential reboots, one per component, those twenty-minute penalties compounded into nearly four hours of idle waiting per server.
No searching games: Declare my boot interface
After tracing the boot sequence and isolating the timeout pattern, the root cause became clear: the servers were blindly searching through every available network boot interface, one by one, waiting for each to fail before moving on. The fix was to eliminate the guesswork entirely — declare the correct boot interface upfront so the system never wastes time on interfaces that will never respond.
But putting this into practice was far from straightforward. As we explain next, we hit several obstacles: the order of our boot automation workflow, a setting we were blocked from changing, and differing string formats from our different network interface card vendors.
Our boot automation workflow
Our boot automaton flow is in three broad stages: firmware initialization, pre-boot, and kernel startup. After power on, the UEFI firmware does some hardware and peripheral initialization followed by the PXE pre-boot environment. The pre-boot sets up the network card and executes a small program called bootloader, which kickstarts the kernel. It’s in this PXE stage that various network interfaces are probed for the right one. On first boot, firmware upgrades are included in our boot automation workflow.
And because each firmware upgrade requires a reboot (and its attendant network boot attempt sequence), that’s how we got to the situation where the total boot time took close to four hours.
By restructuring the automation sequence to declare the network boot interface order early on in the pre-boot PXE stage for each hardware/use-case, we were able to cut the total time by about an hour, since the boot process no longer needed to spend 20 minutes probing for each firmware upgrade.
Attempting to declare the network boot interface order introduced two specific constraints:
Legacy Support: Boot ordering is not supported on older UEFI versions
Persistence: Configuration settings are often reset following a UEFI firmware upgrade
To address these edge cases, we implemented a state validation step. The firmware automation now validates the configuration post-change: if it detects that settings have been modified, it re-applies the config and triggers a reboot.
Although the first boot may take slightly longer, this change drastically reduces the time required for all future start-ups from about 20 minutes to less than a minute per subsequent boot.
Setting the boot order disabled by the vendor
The internal data structure of the Network Boot settings is an EFI_IFR_REF3 data structure that was being lazy loaded, meaning the data is not instantiated until it is explicitly accessed via a GUI callback:
While this is standard industry practice to accelerate BIOS boot times, it rendered the “Network Boot Interface” invisible to our programmatic scans. Because the structure hadn’t been “loaded” yet, our automation couldn’t discover the priorities.
We worked with our vendors to enable specific tokens within the fixed “Boot Order Module.” This forces the discovery of the Network Boot Interface during the boot sequence without requiring manual GUI interaction.
The UEFI from our equipment manufacturers had an immutable setting, Force Priority Httpv4 Httpv6 Pxev4 Pxev6, that was preventing us from changing the boot order.
This required a new BIOS version from our vendor and a debug session when setting the boot order.
Different strings from different network interface card vendors
Depending on the network interface card (NIC) vendor, the strings would be different, causing a mismatch when configuring the boot order through iPXE.
In order to work around this issue, we had to implement an additional feature to the CfHIIConfig_App tool, allowing it to set the config without having the full string:
.*HTTP.*IPv4.*P1
The config would then be matched against the accepted config strings and would select the correct boot order. We are currently working with our UEFI vendors to standardize the network interface strings to only make use of the relevant information (e.g. protocol, transfer type, port number, and physical slot index) and drop the product details like the MAC address. The product details, if needed, can be read from the embedded vital product detail information of the network interface card. That way we eliminate both configuration drift and the use of wildcards.
Inability to check the config via iPXE
Since iPXE reads this variable as HEX, it was reading the string output as hex. To check if the network boot setting was modified and to reduce boot time (so we don’t have to print the variables before setting them), we implemented a boolean flag, uefi-same-hex, to indicate whether a configuration changed.
This enabled us to run a single set command instead of first running show to compare, and then set if the configuration was not in the desired state.
This enabled us to run a single set command instead of first running show to compare, and then set if the configuration was not in the desired state.
# construct path to read the update variable
set buffer-var-guid 91468514-75bc-4bb5-8f33-91efff9e9b1f
set var-upd-path efivar/CfHIIVarUpd-${buffer-var-guid}

#Run the config change command
imgexec <signed CF UEFI configuration App> set ${uefi-setting}=${uefi-value}

#Compare the update variable with the expected value if it has changed.
#If it has changed, set the local variable to reboot the system
iseq ${uefi-same-hex} ${${var-upd-path}} || set has-changed ${uefi-diff-hex}
The result: a more dynamic system
By eliminating the guesswork from our network boot sequence, we turned a four-hour ordeal back into a 3-minute process. The result is a system where changes are dynamic and no manual BIOS interactions are needed. A single BIOS firmware image serves all SKUs, configuration updates deploy at scale through our existing release pipeline, and the entire workflow operates from iPXE.
Metric
Before ordering change
After ordering change
Firmware Upgrade Automation
Nearly 4 hours
3 minutes
Subsequent Single Boot
About 20 minutes
Less than a minute
None of this would have been possible without digging deep into UEFI internals, collaborating closely with our OEM vendors to unlock capabilities like programmatic boot order control, and leveraging open-source tools like iPXE to build scalable automation.
With each passing day, Cloudflare’s OpenBMC team continues to learn about, experiment with, and optimize the boot process across our core fleet. If you are managing bare-metal infrastructure and struggling with slow server boot times, we hope this post has given you a practical framework for identifying and eliminating unnecessary delays in your own network boot sequence. For those interested in learning more about iPXE and network boot automation, check it out here!
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.