Tag Archives: announcements

Removing header remapping from Amazon API Gateway, and notes about our work with security researchers

Post Syndicated from Mark Ryland original https://aws.amazon.com/blogs/security/removing-header-remapping-from-amazon-api-gateway-and-notes-about-our-work-with-security-researchers/

At Amazon Web Services (AWS), our APIs and service functionality are a promise to our customers, so we very rarely make breaking changes or remove functionality from production services. Customers use the AWS Cloud to build solutions for their customers, and when disruptive changes are made or functionality is removed, the downstream impacts can be significant. As builders, we’ve felt the impact of these types of changes ourselves, and we work hard to avoid these situations whenever possible.

When we do need to make breaking changes, we try to provide a smooth path forward for customers who were using the old functionality. Often that means changing the behavior for new users or new deployments, and then allowing a transition window for existing customers to migrate from the old to the new behavior. There are many examples of this pattern, such as an update to IAM role trust policy behavior that we made last year.

This post explains one such recent change that we’ve made in Amazon API Gateway. We also discuss how we work with the security research community to improve things for customers.

Summary and customer impact

Recently, researchers at Omegapoint disclosed an edge case issue with how API Gateway handled HTTP header remapping with custom authorizers based on AWS Lambda. As is often the case with security research, this work generated a second, tangentially related authorization-caching issue that the Omegapoint team also reported.

After analyzing these reports, the API Gateway team decided to remove a documented feature from the service and to adjust another behavior to improve service behavior. We’ve made the appropriate changes to the API Gateway documentation.

As of June 14, 2023, the header remapping feature is no longer available in API Gateway. Customers can still use Velocity Template Language-based (VTL) transformations for header remapping, because this approach wasn’t impacted by the reported issue. If you’re using this design pattern in API Gateway and have questions about this change, reach out to your AWS support team.

The authorization-caching behavior was working as originally designed; but based on the report, we’ve adjusted it to better meet customer expectations.

The team at Omegapoint has published their findings in the blog post Writeup: AWS API Gateway header smuggling and cache confusion.

Before we removed the feature, we contacted customers who were using the direct HTTP header remapping feature through email and the AWS Health Dashboard. If you haven’t been contacted, no action is required on your part.

More details

The main issue that Omegapoint reported was related to a documented, client-controlled HTTP header remapping feature in API Gateway. This feature allowed customers to use one set of header values in the interaction between their clients and API Gateway, and a different set of header values from API Gateway to the backend. The client could send two sets of header values: one for API Gateway and one for the backend. API Gateway would process both sets, but then remap (overwrite) one set of values with another set. This feature was especially useful when allowing newly created API Gateway clients to continue to work with legacy servers whose header-handling logic couldn’t be modified.

The report from Omegapoint highlighted that customers who relied on Lambda authorizers for request-based authorization could be surprised when the remapping feature was used to overwrite header values that were used for further authorization on the backend, which could potentially lead to unintended access. The Lambda authorizer itself worked as expected on unmapped headers, but if there was additional authorization logic in the backend, it could be impacted by a misbehaving client.

The second issue that Omegapoint reported was related to the caching behavior in API Gateway for authorization policies. Previously, the caching method might reuse a cached authorization with a different value when the <method.request.multivalueheader.*> value was used in the request header within the time-to-live (TTL) of the cached value. This was the expected behavior of the wildcard value.

However, after reviewing the report, we agreed that it could surprise customers, and potentially allow misbehaving clients to bypass expected authorization. We were able to change this behavior without customer impact, because there is no evidence of customers relying on this behavior. So now, cached authorizations are no longer used in the <multivalueheader> case.

How we work with researchers

Security researchers regularly submit vulnerability reports to AWS Security. Some researchers are independent, some work in academic institutions, and others work in AWS partner or customer organizations. Our Outreach team triages submissions rapidly. Upon receipt, we start a conversation and work closely with researchers to understand their concerns, give our perspective, and agree on the best path forward.

If technical changes are required, our services and security teams work together to determine and implement the appropriate remediations based on the potential impact. They work with affected customers to reduce or eliminate impacts, and they work with the researchers to coordinate the publication of their findings.

Often these reports highlight situations where the designed and documented behavior might result in a surprising outcome for some customers. In those cases, we work with the researcher to make the appropriate updates to the documentation, if needed, and help ensure that the researcher’s finding is published with customer education as the primary goal.

In other cases, where warranted, we communicate about security issues to the broader customer and security community by using a security bulletin. Finally, we publish security blog posts in cases where providing more context makes sense, such as the current issue.

Security is our top priority, and working with the community to make our customers and the AWS Cloud safer is a key part of that. Clear communication helps build understanding and trust.

Working together

We removed the direct remapping feature because not many customers were using it, and we felt that documentation warning against the impacted design choices provided insufficient visibility and protection for customers. We designed and released the feature in an era when it was reasonable to assume that an API Gateway client would be well-behaved, but as times change, it now makes sense that an API client could be potentially negligent or even hostile. There are multiple alternative approaches that can provide the same outcome for customers, but in a more expected and controlled manner, which made this a simpler process to work through.

When researchers report potential security findings, we work through our process to determine the best outcome for our customers. In most cases, we can adjust designs to address the issue, while maintaining the affected features.

In rare cases, such as this one, the more effective path forward is to sunset a feature in favor of a more expected and secure approach. This is a core principle of evolving architectures and building resilient systems. It’s something that we practice regularly at AWS and a key principle that we share with our customers and the community through the AWS Well-Architected Framework.

Our thanks to the team at Omegapoint for reporting these issues, and to all of the researchers who continue to work with us to help make the AWS Cloud safer for our customers.

Want more AWS Security news? Follow us on Twitter.

Mark Ryland

Mark Ryland

Mark is the director of the Office of the CISO for AWS. He has over 30 years of experience in the technology industry, and has served in leadership roles in cybersecurity, software engineering, distributed systems, technology standardization, and public policy. Previously, he served as the Director of Solution Architecture and Professional Services for the AWS World Public Sector team.

Prevent account creation fraud with AWS WAF Fraud Control – Account Creation Fraud Prevention

Post Syndicated from David MacDonald original https://aws.amazon.com/blogs/security/prevent-account-creation-fraud-with-aws-waf-fraud-control-account-creation-fraud-prevention/

Threat actors use sign-up pages and login pages to carry out account fraud, including taking unfair advantage of promotional and sign-up bonuses, publishing fake reviews, and spreading malware.

In 2022, AWS released AWS WAF Fraud Control – Account Takeover Prevention (ATP) to help protect your application’s login page against credential stuffing attacks, brute force attempts, and other anomalous login activities.

Today, we introduce AWS WAF Fraud Control – Account Creation Fraud Prevention (ACFP) to help protect your application’s sign-up pages against fake account creation by detecting and blocking fake account creation requests.

You can now get comprehensive account fraud prevention by combining AWS WAF Account Creation Fraud Prevention and Account Takeover Prevention in your AWS WAF web access control list (web ACL). In this post, we will show you how to set up AWS WAF with ACFP for your application sign-up pages.

Overview of Account Creation Fraud Prevention for AWS WAF

ACFP helps protect your account sign-up pages by continuously monitoring requests for anomalous digital activity and automatically blocking suspicious requests based on request identifiers, behavioral analysis, and machine learning.

ACFP uses multiple capabilities to help detect and block fake account creation requests at the network edge before they reach your application. An automated vetting process for account creation requests uses rules based on reputation and risk to protect your registration pages against use of stolen credentials and disposable email domains. ACFP uses silent challenges and CAPTCHA challenges to identify and respond to sophisticated bots that are designed to actively evade detection.

ACFP is an AWS Managed Rules rule group. If you already use AWS WAF, you can configure ACFP without making architectural changes. On a single configuration page, you specify the registration page request inspection parameters that ACFP uses to detect fake account creation requests, including user identity, address, and phone number.

ACFP uses session tokens to separate legitimate client sessions from those that are not. These tokens allow ACFP to verify that the client applications that sign up for an account are legitimate. The AWS WAF Javascript SDK automatically generates these tokens during the frontend application load. We recommend that you integrate the AWS WAF Javascript SDK into your application, particularly for single-page applications where you don’t want page refreshes.

Walkthrough

In this walkthrough, we will show you how to set up ACFP for AWS WAF to help protect your account sign-up pages against account creation fraud. This walkthrough has two main steps:

  1. Set up an AWS managed rule group for ACFP in the AWS WAF console.
  2. Add the AWS WAF JavaScript SDK to your application pages.

Set up Account Creation Fraud Prevention

The first step is to set up ACFP by creating a web ACL or editing an existing one. You will add the ACFP rule group to this web ACL.

The ACFP rule group requires that you provide your registration page path, account creation path, and optionally the sign-up request fields that map to user identity, address, and phone number. ACFP uses this configuration to detect fraudulent sign-up requests and then decide an appropriate action, including blocking, challenging interstitial during the frontend application load, or requiring a CAPTCHA.

To set up ACFP

  1. Open the AWS WAF console, and then do one of the following:
    • To create a new web ACL, choose Create web ACL.
    • To edit an existing web ACL, choose the name of the ACL.
  2. On the Rules tab, for the Add Rules dropdown, select Add managed rule groups.
  3. Add the Account creation fraud prevention rule set to the web ACL. Then, choose Edit to edit the rule configuration.
  4. For Rule group configuration, provide the following information that the ACFP rule group requires to inspect account creation requests, as shown in Figure 1.
    • For Registration page path, enter the path for the registration page website for your application.
    • For Account creation path, enter the path of the endpoint that accepts the completed registration form.
    • For Request inspection, select whether the endpoint that you specified in Account creation path accepts JSON or FORM_ENCODED payload types.
    Figure 1: Account creation fraud prevention - Add account creation paths

    Figure 1: Account creation fraud prevention – Add account creation paths

  5. (Optional): Provide Field names used in submitted registration forms, as shown in Figure 2. This helps ACFP more accurately identify requests that contain information that is considered stolen, or with a bad reputation. For each field, provide the relevant information that was included in your account creation request. For this walkthrough, we use JSON pointer syntax.
     
    Figure 2: Account creation fraud prevention - Add optional field names

    Figure 2: Account creation fraud prevention – Add optional field names

  6. For Account creation fraud prevention rules, review the actions taken on each category of account creation fraud, and optionally customize them for your web applications. For this walkthrough, we leave the default rule action for each category set to the default action, as shown in Figure 3. If you want to customize the rules, you can select different actions for each category based on your application security needs:
    • Allow — Allows the request to be sent to the protected resource.
    • Block — Blocks the request, returning an HTTP 403 (Forbidden) response.
    • Count — Allows the request to be sent to the protected resource while counting detections. The count shows you bot activity that is occurring without blocking or challenging. When you turn on rules for the first time, this information can help you see what the detections are, before you change the actions.
    • CAPTCHA and Challenge — use CAPTCHA puzzles and silent challenges with tokens to track successful client responses.
    Figure 3: Account creation fraud prevention - Select actions for each category

    Figure 3: Account creation fraud prevention – Select actions for each category

  7. To save the configuration, choose Save.
  8. To add the ACFP rule group to your web ACL, choose Add rules.
  9. (Optional) Include additional rules in your web ACL, as described in the Best practices section that follows.
  10. To create or edit your web ACL, proceed through the remaining configuration pages.

Add the AWS WAF JavaScript SDK to your application pages

The next step is to find the AWS WAF JavaScript SDK and add it to your application pages.

The SDK injects a token in the requests that you send to your protected resources. You must use the SDK integration to fully enable ACFP detections.

To add the SDK to your application pages

  1. In the AWS WAF console, in the left navigation pane, choose Application integration.
  2. Under Web ACLs that are enabled for application integration, choose the name of the web ACL that you created previously.
  3. Under JavaScript SDK, copy the provided code snippet. This code snippet allows for creation of the cryptographic token in the background when the application loads for the first time. Figure 4 shows the SDK link.
    Figure 4: Application integration – Add JavaScript SDK link to application pages

    Figure 4: Application integration – Add JavaScript SDK link to application pages

  4. Add the code snippet to your pages. For example, paste the provided script code within the <head> section of the HTML. For ACFP, you only need to add the code snippet to the registration page, but if you are using other AWS WAF managed rules such as Account Takeover Protection or Targeted Bots on other pages, you will also need to add the code snippet to those pages.
  5. To validate that your application obtains tokens correctly, load your application in a browser and verify that a cookie named aws-waf-token has been set during page load.

Review metrics

Now that you’ve set up the web ACL and integrated the SDK with the application, you can use the bot visualization dashboard in AWS WAF to review fraudulent account creation traffic patterns. ACFP rules emit metrics that correspond to their labels, helping you identify which rule within the ACFP rule group initiated an action. You can also use labels and rule actions to filter AWS WAF logs so that you can further examine a request.

To view AWS WAF metrics for the distribution

  1. In the AWS WAF console, in the left navigation pane, select Web ACLs.
  2. Select the web ACL for which ACFP is enabled, and then choose the Bot Control tab to view the metrics.
  3. In the Filter metrics by dropdown, select Account creation fraud prevention to see the ACFP metrics for your web ACL.
Figure 5: Account creation fraud prevention – Review web ACL metrics

Figure 5: Account creation fraud prevention – Review web ACL metrics

Best practices

In this section, we share best practices for your ACFP rule group setup.

Limit the requests that ACFP evaluates to help lower costs

ACFP evaluates web ACL rules in priority order and takes the action associated with the first rule that a request matches. Requests that match and are blocked by a rule will not be evaluated against lower priority rules. ACFP only evaluates an ACFP rule group if a request matches the registration and account creation URI paths that are specified in the configuration.

You will incur additional fees for requests that ACFP evaluates. To help reduce ACFP costs, use higher priority rules to block requests before the ACFP rule group evaluates them. For example, you can add a higher priority AWS Managed Rules IP reputation rule group to block account creation requests from bots and other threats before ACFP evaluates them. Rate-based rules with a higher priority than the ACFP rule group can help mitigate volumetric account creation attempts by limiting the number of requests that a single IP can make in a five-minute period. For further guidance on rate-based rules, see The three most important AWS WAF rate-based rules.

If you are using the AWS WAF Bot Control rule group, give it a higher priority than the ACFP rule group because it’s less expensive to evaluate.

Use SDK integration

ACFP requires the tokens that the SDK generates. The SDK can generate these tokens silently rather than requiring a redirect or CAPTCHA. Both AWS WAF Bot Control and AWS WAF Fraud Control use the same SDK if both rule groups are in the same web ACL.

These tokens have a default immunity time (otherwise knowns as a timeout) of 5 minutes, after which AWS WAF requires the client to be challenged again. You can use the AWS WAF integration fetch wrapper in your single-pane application to help ensure that the token retrieval completes before the client sends requests to your account creation API without requiring a page refresh. Alternatively, you can use the getToken operation if you are not using fetch.

You can continue to use the CAPTCHA JavaScript API instead if you’ve already integrated this into your application.

Use both ACFP and ATP for comprehensive account fraud prevention

You can help prevent account fraud for both sign-up and login pages by enabling the ATP rule group in the same web ACL as ACFP.

Test ACFP before you deploy it to production

Test and tune your ACFP implementation in a staging or testing environment to help avoid negatively impacting legitimate users. We recommend that you start by deploying your rules in count mode in production to understand potential impact to your traffic before switching them back to the default rule actions. Use the default ACFP rule group actions when you deploy the web ACL to production. For further guidance, see Testing and Deploying ACFP.

Pricing and availability

ACFP is available today on Amazon CloudFront and in 22 AWS Regions. For information on availability and pricing, see AWS WAF Pricing.

Conclusion

In this post, we showed you how to use ACFP to protect your application’s sign-up pages against fake account creation. You can now combine ACFP with ATP managed rules in a single web ACL for comprehensive account fraud prevention. For more information and to get started today, see the AWS WAF Developer Guide.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

David MacDonald

David MacDonald

David is a Senior Solutions Architect focused on helping New Zealand startups build secure and scalable solutions. He has spent most of his career building and operating SaaS products that serve a variety of industries. Outside of work, David is an amateur farmer, and tends to a small herd of alpacas and goats.

Geary Scherer

Geary Scherer

Geary is a Solutions Architect focused on Travel and Hospitality customers in the Southeast US. He holds all 12 current AWS certifications and loves to dive into complex Edge Services use cases to help AWS customers, especially around Bot Mitigation. Outside of work, Geary enjoys playing soccer and cheering his daughters on at dance and softball competitions.

AWS Security Hub launches a new capability for automating actions to update findings

Post Syndicated from Stuart Gregg original https://aws.amazon.com/blogs/security/aws-security-hub-launches-a-new-capability-for-automating-actions-to-update-findings/

If you’ve had discussions with a security organization recently, there’s a high probability that the word automation has come up. As organizations scale and consume the benefits the cloud has to offer, it’s important to factor in and understand how the additional cloud footprint will affect operations. Automation is a key enabler for efficient operations and can help drive down the number of repetitive tasks that the operational teams have to perform.

Alert fatigue is caused when humans work on the same repetitive tasks day in and day out and also have a large volume of alerts that need to be addressed. The repetitive nature of these tasks can cause analysts to become numb to the importance of the task or make errors due to manual processing. This can lead to misclassification of security alerts or higher-severity alerts being overlooked due to investigation times. Automation is key here to reduce the number of repetitive tasks and give analysts time to focus on other areas of importance.

In this blog post, we’ll walk you through new capabilities within AWS Security Hub that you can use to take automated actions to update findings. We’ll show you some example scenarios that use this capability and set you up with the knowledge you need to get started with creating automation rules.

Automation rules in Security Hub

AWS Security Hub is available globally and is designed to give you a comprehensive view of your security posture across your AWS accounts. With Security Hub, you have a single place that aggregates, organizes, and prioritizes your security alerts, or findings, from multiple AWS services, including Amazon GuardDuty, Amazon Inspector, Amazon Macie, AWS Firewall Manager, AWS Systems Manager Patch Manager, AWS Config, AWS Health, and AWS Identity and Access Management (IAM) Access Analyzer, as well as from over 65 AWS Partner Network (APN) solutions.

Previously, Security Hub could take automated actions on findings, but this involved going to the Amazon EventBridge console or API, creating an EventBridge rule, and then building an AWS Lambda function, an AWS Systems Manager Automation runbook, or an AWS Step Functions step as the target of that rule. If you wanted to set up these automated actions in the administrator account and home AWS Region and run them in member accounts and in linked Regions, you would also need to deploy the correct IAM permissions to enable the actions to run across accounts and Regions. After setting up the automation flow, you would need to maintain the EventBridge rule, Lambda function, and IAM roles. Such maintenance could include upgrading the Lambda versions, verifying operational efficiency, and checking that everything is running as expected.

With Security Hub, you can now use rules to automatically update various fields in findings that match defined criteria. This allows you to automatically suppress findings, update findings’ severities according to organizational policies, change findings’ workflow status, and add notes. As findings are ingested, automation rules look for findings that meet defined criteria and update the specified fields in findings that meet the criteria. For example, a user can create a rule that automatically sets the finding’s severity to “Critical” if the finding account ID is of a known business-critical account. A user could also automatically suppress findings for a specific control in an account where the finding represents an accepted risk.

With automation rules, Security Hub provides you a simplified way to build automations directly from the Security Hub console and API. This reduces repetitive work for cloud security and DevOps engineers and can reduce the mean time to response.

Use cases

In this section, we’ve put together some examples of how Security Hub automation rules can help you. There’s a lot of flexibility in how you can use the rules, and we expect there will be many variations that your organization will use when contextual information about security risk has been added.

Scenario 1: Elevate finding severity for specific controls based on account IDs

Security Hub offers protection by using hundreds of security controls that create findings that have a severity associated with them. Sometimes, you might want to elevate that severity according to your organizational policies or according to the context of the finding, such as the account it relates to. With automation rules, you can now automatically elevate the severity for specific controls when they are in a specific account.

For example, the AWS Foundational Security Best Practices control GuardDuty.1 has a “High” severity by default. But you might consider such a finding to have “Critical” severity if it occurs in one of your top production accounts. To change the severity automatically, you can choose GeneratorId as a criteria and check that it’s equal to aws-foundational-security-best-practices/v/1.0.0/GuardDuty.1, and also add AwsAccountId as a criteria and check that it’s equal to YOUR_ACCOUNT_IDs. Then, add an action to update the severity to “Critical,” and add a note to the person who will look at the finding that reads “Urgent — look into these production accounts.”

You can set up this automation rule through the AWS CLI, the console, the Security Hub API, or the AWS SDK for Python (Boto3), as follows.

To set up the automation rule for Scenario 1 (AWS CLI)

  • In the AWS CLI, run the following command to create a new automation rule with a specific Amazon Resource Name (ARN). Note the different modifiable parameters:
    • Rule-name — The name of the rule that will be created.
    • Rule-status — An optional parameter. Specify whether you want Security Hub to activate and start applying the rule to findings after creation. If no value is specified, the default value is ENABLED. A value of DISABLED means that the rule will be paused after creation.
    • Rule-order — Provide the processing order for the rule. Security Hub applies rules with a lower numerical value for this parameter first.
    • Criteria — Provide the criteria that you want Security Hub to use to filter your findings. The rule action will be applied to findings that match the criteria. For a list of supported criteria, see Criteria and actions for automation rules. In this example, the criteria are placeholders and should be replaced.
    • Actions — Provide the actions that you want Security Hub to take when there’s a match between a finding and your defined criteria. For a list of supported actions, see Criteria and actions for automation rules. In this example, the actions are placeholders and should be replaced.
    aws securityhub create-automation-rule \—rule-name "Elevate severity for findings in production accounts - GuardDuty.1" \—rule-status "ENABLED"" \—rule-order 1 \—description "Elevate severity for findings in production accounts - GuardDuty.1" \—criteria '{"GeneratorId": [{"Value": "aws-foundational-security-best-practices/v/1.0.0/GuardDuty.1","Comparison": "EQUALS"}, "AwsAccountId": [{"Value": "<111122223333>","Comparison": "EQUALS"},]}' \—actions '[{"Type": "FINDING_FIELDS_UPDATE","FindingFieldsUpdate": {"Severity": {"Label": "CRITICAL"},"Note": {"Text": "Urgent – look into these production accounts","UpdatedBy": "sechub-automation"}}}]' \—region us-east-1

To set up the automation rule for Scenario 1 (console)

  1. Open the Security Hub console, and in the left navigation pane, choose Automations.
    Figure 1: Automation rules in the Security Hub console

    Figure 1: Automation rules in the Security Hub console

  2. Choose Create rule, and then choose Create a custom rule to get started with creating a rule of your choice. Add a rule name and description.
    Figure 2: Create a new custom rule

    Figure 2: Create a new custom rule

  3. Under Criteria, add the following information.
    • Key 1
      • Key = GeneratorID
      • Operator = EQUALS
      • Value = aws-foundational-security-best-practices/v/1.0.0/GuardDuty.1
    • Key 2
      • Key = AwsAccountId
      • Operator = EQUALS
      • Value = Your AWS account ID
    Figure 3: Information added for the rule criteria

    Figure 3: Information added for the rule criteria

  4. You can preview which findings will match the criteria by looking in the preview section.
    Figure 4: Preview section

    Figure 4: Preview section

  5. Next, under Automated action, specify which finding value to update automatically when findings match your criteria.
    Figure 5: Automated action to be taken against the findings that match the criteria

    Figure 5: Automated action to be taken against the findings that match the criteria

  6. For Rule status, choose Enabled, and then choose Create rule.
    Figure 6: Set the rule status to Enabled

    Figure 6: Set the rule status to Enabled

  7. After you choose Create rule, you will see the newly created rule within the Automations portal.
    Figure 7: Newly created rule within the Security Hub Automations page

    Figure 7: Newly created rule within the Security Hub Automations page

    Note: In figure 7, you can see multiple automation rules. When you create automation rules, you assign each rule an order number. This determines the order in which Security Hub applies your automation rules. This becomes important when multiple rules apply to the same finding or finding field. When multiple rule actions apply to the same finding field, the rule with the highest numerical value for rule order is applied last and has the ultimate effect on that field.

Additionally, if your preferred deployment method is to use the API or AWS SDK for Python (Boto3), we have information on how you can use these means of deployment in our public documentation.

Scenario 2: Change the finding severity to high if a resource is important, based on resource tags

Imagine a situation where you have findings associated to a wide range of resources. Typically, organizations will attempt to prioritize which findings to remediate first. You can achieve this prioritization through Security Hub and the contextual fields that are available for you to use — for example, by using the severity of the finding or the account ID the resource is sitting in. You might also have your own prioritization based on other factors. You could add this additional context to findings by using a tagging strategy. With automation rules, you can now automatically elevate the severity for specific findings based on the tag value associated to the resource.

For example, if a finding comes into Security Hub with the severity rating “Medium,” but the resource in question is critical to the business and has the tag production associated to it, you could automatically raise the severity rating to “High.”

Note: This will work only for findings where there is a resource tag associated with the finding.

Scenario 3: Suppress GuardDuty findings with a severity of “Informational”

GuardDuty provides an overarching view of the state of threats to deployed resources in your organization’s cloud environment. After evaluation, GuardDuty produces findings related to these threats. The findings produced by GuardDuty have different severities, to help organizations with prioritization. Some of these findings will be given an “Informational” severity. “Informational” indicates that no issue was found and the content of the finding is purely to give information. After you have evaluated the context of the finding, you might want to suppress any additional findings that match the same criteria.

For example, you might want to set up a rule so that new findings with the generator ID that produced “Informational” findings are suppressed, keeping only the findings that need action.

Templates

When you create a new rule, you can also choose to create a rule from a template. These templates are regularly updated with use cases that are applicable for many customers.

To set up an automation rule by using a template from the console

  1. In the Security Hub console, choose Automations, and then choose Create rule.
  2. Choose Create a rule from a template to get started with creating a rule of your choice.
  3. Select a rule template from the drop-down menu.
    Figure 8: Select an automation rule template

    Figure 8: Select an automation rule template

  4. (Optional) If necessary, modify the Rule, Criteria, and Automated action sections.
  5. For Rule status, choose whether you want the rule to be enabled or disabled after it’s created.
  6. (Optional) Expand the Additional settings section. Choose Ignore subsequent rules for findings that match these criteria if you want this rule to be the last rule applied to findings that match the rule criteria.
  7. (Optional) For Tags, add tags as key-value pairs to help you identify the rule.
  8. Choose Create rule.

Multi-Region deployment

For organizations that operate in multiple AWS Regions, we’ve provided a solution that you can use to replicate rules created in your central Security Hub admin account into these additional Regions. You can find the sample code for this solution in our GitHub repo.

Conclusion

In this blog post, we’ve discussed the importance of automation and its ability to help organizations scale operations within the cloud. We’ve introduced a new capability in AWS Security Hub, automation rules, that can help reduce the repetitive tasks your operational teams may be facing, and we’ve showcased some example use cases to get you started. Start using automation rules in your environment today. We’re excited to see what use cases you will solve with this feature and as always, are happy to receive any feedback.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.

Stuart Gregg

Stuart Gregg

Stuart enjoys providing thought leadership and being a trusted advisor to customers. In his spare time Stuart can be seen either training for an Ironman or snacking.

Shachar Hirshberg

Shachar Hirshberg

Shachar is a Senior Product Manager at AWS Security Hub with over a decade of experience in building, designing, launching, and scaling enterprise software. He is passionate about further improving how customers harness AWS services to enable innovation and enhance the security of their cloud environments. Outside of work, Shachar is an avid traveler and a skiing enthusiast.

New – Amazon S3 Dual-Layer Server-Side Encryption with Keys Stored in AWS Key Management Service (DSSE-KMS)

Post Syndicated from Irshad Buchh original https://aws.amazon.com/blogs/aws/new-amazon-s3-dual-layer-server-side-encryption-with-keys-stored-in-aws-key-management-service-dsse-kms/

Today, we are launching Amazon S3 dual-layer server-side encryption with keys stored in AWS Key Management Service (DSSE-KMS), a new encryption option in Amazon S3 that applies two layers of encryption to objects when they are uploaded to an Amazon Simple Storage Service (Amazon S3) bucket. DSSE-KMS is designed to meet National Security Agency CNSSP 15 for FIPS compliance and Data-at-Rest Capability Package (DAR CP) Version 5.0 guidance for two layers of CNSA encryption. Using DSSE-KMS, you can fulfill regulatory requirements to apply multiple layers of encryption to your data.

Amazon S3 is the only cloud object storage service where customers can apply two layers of encryption at the object level and control the data keys used for both layers. DSSE-KMS makes it easier for highly regulated customers to fulfill rigorous security standards, such as US Department of Defense (DoD) customers.

With DSSE-KMS, you can specify dual-layer server-side encryption (DSSE) in the PUT or COPY request for an object or configure your S3 bucket to apply DSSE to all new objects by default. You can also enforce DSSE-KMS using IAM and bucket policies. Each layer of encryption uses a separate cryptographic implementation library with individual data encryption keys. DSSE-KMS helps protect sensitive data against the low probability of a vulnerability in a single layer of cryptographic implementation.

DSSE-KMS simplifies the process of applying two layers of encryption to your data, without having to invest in infrastructure required for client-side encryption. Each layer of encryption uses a different implementation of the 256-bit Advanced Encryption Standard with Galois Counter Mode (AES-GCM) algorithm. DSSE-KMS uses the AWS Key Management Service (AWS KMS) to generate data keys, allowing you to control your customer managed keys by setting permissions per key and specifying key rotation schedules. With DSSE-KMS, you can now query and analyze your dual-encrypted data with AWS services such as Amazon Athena, Amazon SageMaker, and more.

With this launch, Amazon S3 now offers four options for server-side encryption:

  1. Server-side encryption with Amazon S3 managed keys (SSE-S3)
  2. Server-side encryption with AWS KMS (SSE-KMS)
  3. Server-side encryption with customer-provided encryption keys (SSE-C)
  4. Dual-layer server-side encryption with keys stored in KMS (DSSE-KMS)

Let’s see how DSSE-KMS works in practice.

Create an S3 Bucket and Turn on DSSE-KMS
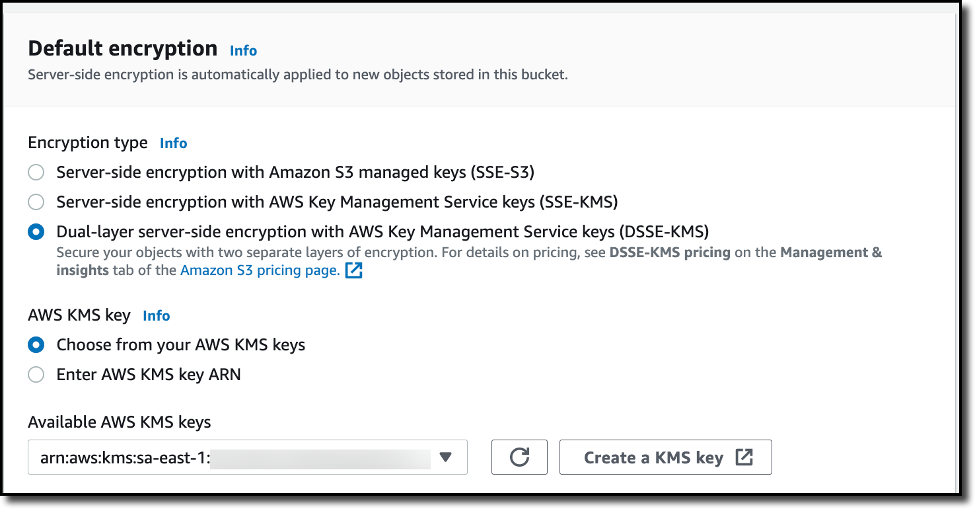
To create a new bucket in the Amazon S3 console, I choose Buckets in the navigation pane. I choose Create bucket, and I select a unique and meaningful name for the bucket. Under Default encryption section, I choose DSSE-KMS as the encryption option. From the available AWS KMS keys, I select a key for my requirements. Finally, I choose Create bucket to complete the creation of the S3 bucket, encrypted by DSSE-KMS encryption settings.

Encryption

Upload an Object to the DSSE-SSE enabled S3 Bucket
In the Buckets list, I choose the name of the bucket that I want to upload an object to. On the Objects tab for the bucket, I choose Upload. Under Files and folders, I choose Add files. I then choose a file to upload, and then choose Open. Under Server-side encryption, I choose Do not specify an encryption key. I then choose Upload.

Server Side Encryption

Once the object is uploaded to the S3 bucket, I notice that the uploaded object inherits the Server-side encryption settings from the bucket.

Server Side Encryption Setting

Download a DSSE-KMS Encrypted Object from an S3 Bucket
I select the object that I previously uploaded and choose Download or choose Download as from the Object actions menu. Once the object is downloaded, I open it locally, and the object is decrypted automatically, requiring no change to client applications.

Now Available
Amazon S3 dual-layer server-side encryption with keys stored in AWS KMS (DSSE-KMS) is available today in all AWS Regions. You can get started with DSSE-KMS via the AWS CLI or AWS Management Console. To learn more about all available encryption options on Amazon S3, visit the Amazon S3 User Guide. For pricing information on DSSE-KMS, visit the Amazon S3 pricing page (Storage tab) and the AWS KMS pricing page.

— Irshad

Simplify How You Manage Authorization in Your Applications with Amazon Verified Permissions – Now Generally Available

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/simplify-how-you-manage-authorization-in-your-applications-with-amazon-verified-permissions-now-generally-available/

When developing a new application or integrating an existing one into a new environment, user authentication and authorization require significant effort to be correctly implemented. In the past, you would have built your own authentication system, but today you can use an external identity provider like Amazon Cognito. Yet, authorization logic is typically implemented in code.

This might begin simply enough, with all users assigned a role for their job function. However, over time, these permissions grow increasingly complex. The number of roles expands, as permissions become more fine-grained. New use cases drive the need for custom permissions. For instance, one user might share a document with another in a different role, or a support agent might require temporary access to a customer account to resolve an issue. Managing permissions in code is prone to errors, and presents significant challenges when auditing permissions and deciding who has access to what, particularly when these permissions are expressed in different applications and using multiple programming languages.

At re:Invent 2022, we introduced in preview Amazon Verified Permissions, a fine-grained permissions management and authorization service for your applications that can be used at any scale. Amazon Verified Permissions centralizes permissions in a policy store and helps developers use those permissions to authorize user actions within their applications. Similar to how an identity provider simplifies authentication, a policy store let you manage authorization in a consistent and scalable way.

To define fine-grained permissions, Amazon Verified Permissions uses Cedar, an open-source policy language and software development kit (SDK) for access control. You can define a schema for your authorization model in terms of principal types, resource types, and valid actions. In this way, when a policy is created, it is validated against your authorization model. You can simplify the creation of similar policies using templates. Changes to the policy store are audited so that you can see of who made the changes and when.

You can then connect your applications to Amazon Verified Permissions through AWS SDKs to authorize access requests. For each authorization request, the relevant policies are retrieved and evaluated to determine whether the action is permitted or not. You can reproduce those authorization requests to confirm that permissions work as intended.

Today, I am happy to share that Amazon Verified Permissions is generally available with new capabilities and a simplified user experience in the AWS Management Console.

Let’s see how you can use it in practice.

Creating a Policy Store with Amazon Verified Permissions
In the Amazon Verified Permissions console, I choose Create policy store. A policy store is a logical container that stores policies and schema. Authorization decisions are made based on all the policies present in a policy store.

To configure the new policy store, I can use different methods. I can start with a guided setup, a sample policy store (such as for a photo-sharing app, an online store, or a task manager), or an empty policy store (recommended for advanced users). I select Guided setup, enter a namespace for my schema (MyApp), and choose Next.

Console screenshot.

Resources are the objects that principals can act on. In my application, I have Users (principals) that can create, read, update, and delete Documents (resources). I start to define the Documents resource type.

I enter the name of the resource type and add two required attributes:

  • owner (String) to specify who is the owner of the document.
  • isPublic (Boolean) to flag public documents that anyone can read.

Console screenshot.

I specify four actions for the Document resource type:

  • DocumentCreate
  • DocumentRead
  • DocumentUpdate
  • DocumentDelete

Console screenshot.

I enter User as the name of the principal type that will be using these actions on Documents. Then, I choose Next.

Console screenshot.

Now, I configure the User principal type. I can use a custom configuration to integrate an external identity source, but in this case, I use an Amazon Cognito user pool that I created before. I choose Connect user pool.

Console screenshot.

In the dialog, I select the AWS Region where the user pool is located, enter the user pool ID, and choose Connect.

Console screenshot.

Now that the Amazon Cognito user pool is connected, I can add another level of protection by validating the client application IDs. For now, I choose not to use this option.

In the Principal attributes section, I select which attributes I am planning to use for attribute-based access control in my policies. I select sub (the subject), used to identify the end user according to the OpenID Connect specification. I can select more attributes. For example, I can use email_verified in a policy to give permissions only to Amazon Cognito users whose email has been verified.

Console screenshot.

As part of the policy store creation, I create a first policy to give read access to user danilop to the doc.txt document.

Console screenshot.

In the following code, the console gives me a preview of the resulting policy using the Cedar language.

permit(
  principal == MyApp::User::"danilop",
  action in [MyApp::Action::"DocumentRead"],
  resource == MyApp::Document::"doc.txt"
) when {
  true
};

Finally, I choose Create policy store.

Adding Permissions to the Policy Store
Now that the policy store has been created, I choose Policies in the navigation pane. In the Create policy dropdown, I choose Create static policy. A static policy contains all the information needed for its evaluation. In my second policy, I allow any user to read public documents. By default everything is forbidden, so in Policy Effect I choose Permit.

In the Policy scope, I leave All principals and All resources selected, and select the DocumentRead action. In the Policy section, I change the when condition clause to limit permissions to resources where isPublic is equal to true:

permit (
  principal,
  action in [MyApp::Action::"DocumentRead"],
  resource
)
when { resource.isPublic };

I enter a description for the policy and choose Create policy.

For my third policy, I create another static policy to allow full access to the owner of a document. Again, in Policy Effect, I choose Permit and, in the Policy scope, I leave All principals and All resources selected. This time, I also leave All actions selected.

In the Policy section, I change the when condition clause to limit permissions to resources where the owner is equal to the sub of the principal:

permit (principal, action, resource)
when { resource.owner == principal.sub };

In my application, I need to allow read access to specific users that are not owners of a document. To simplify that, I create a policy template. Policy templates let me create policies from a template that uses placeholders for some of their values, such as the principal or the resource. The placeholders in a template are keywords that start with the ? character.

In the navigation pane, I choose Policy templates and then Create policy template. I enter a description and use the following policy template body. When using this template, I can specify the value for the ?principal and ?resource placeholders.

permit(
  principal == ?principal,
  action in [MyApp::Action::"DocumentRead"],
  resource == ?resource
);

I complete the creation of the policy template. Now, I use the template to simplify the creation of policies. I choose Policies in the navigation pane, and then Create a template-linked policy in the Create policy dropdown. I select the policy template I just created and choose Next.

To give access to a user (danilop) for a specific document (new-doc.txt), I just pass the following values (note that MyApp is the namespace of the policy store):

  • For the Principal: MyApp::User::"danilop"
  • For the Resource: MyApp::Document::"new-doc.txt"

I complete the creation of the policy. It’s now time to test if the policies work as expected.

Testing Policies in the Console
In my applications, I can use the AWS SDKs to run an authorization request. The console provides a way to to simulate what my applications would do. I choose Test bench in the navigation pane. To simplify testing, I use the Visual mode. As an alternative, I have the option to use the same JSON syntax as in the SDKs.

As Principal, I pass the janedoe user. As Resource, I use requirements.txt. It’s not a public document (isPublic is false) and the owner attribute is equal to janedoe‘s sub. For the Action, I select MyApp::Action::"DocumentUpdate".

When running an authorization request, I can pass Additional entities with more information about principals and resources associated with the request. For now, I leave this part empty.

I choose Run authorization request at the top to see the decision based on the current policies. As expected, the decision is allow. Here, I also see which policies hav been satisfied by the authorization request. In this case, it is the policy that allows full access to the owner of the document.

I can test other values. If I change the owner of the document and the action to DocumentRead, the decision is deny. If I then set the resource attribute isPublic to true, the decision is allow because there is a policy that permits all users to read public documents.

Handling Groups in Permissions
The administrative users in my application need to be able to delete any document. To do so, I create a role for admin users. First, I choose Schema in the navigation pane and then Edit schema. In the list of entity types, I choose to add a new one. I use Role as Type name and add it. Then, I select User in the entity types and edit it to add Role as a parent. I save changes and create the following policy:

permit (
  principal in MyApp::Role::"admin",
  action in [MyApp::Action::"DocumentDelete"],
  resource
);

In the Test bench, I run an authorization request to check if user jeffbarr can delete (DocumentDelete) resource doc.txt. Because he’s not the owner of the resource, the request is denied.

Now, in the Additional entities, I add the MyApp::User entity with jeffbarr as identifier. As parent, I add the MyApp::Role entity with admin as identifier and confirm. The console warns me that entity MyApp::Role::"admin" is referenced, but it isn’t included in additional entities data. I choose to add it and fix this issue.

I run an authorization request again, and it is now allowed because, according to the additional entities, the principal (jeffbarr) is an admin.

Using Amazon Verified Permissions in Your Application
In my applications, I can run an authorization requests using the isAuthorized API action (or isAuthrizedWithToken, if the principal comes from an external identity source).

For example, the following Python code uses the AWS SDK for Python (Boto3) to check if a user has read access to a document. The authorization request uses the policy store I just created.

import boto3
import time

verifiedpermissions_client = boto3.client("verifiedpermissions")

POLICY_STORE_ID = "XAFTHeCQVKkZhsQxmAYXo8"

def is_authorized_to_read(user, resource):

    authorization_result = verifiedpermissions_client.is_authorized(
        policyStoreId=POLICY_STORE_ID, 
        principal={"entityType": "MyApp::User", "entityId": user}, 
        action={"actionType": "MyApp::Action", "actionId": "DocumentRead"},
        resource={"entityType": "MyApp::Document", "entityId": resource}
    )

    print('Can {} read {} ?'.format(user, resource))

    decision = authorization_result["decision"]

    if decision == "ALLOW":
        print("Request allowed")
        return True
    else:
        print("Request denied")
        return False

if is_authorized_to_read('janedoe', 'doc.txt'):
    print("Here's the doc...")

if is_authorized_to_read('danilop', 'doc.txt'):
    print("Here's the doc...")

I run this code and, as you can expect, the output is in line with the tests run before.

Can janedoe read doc.txt ?
Request denied
Can danilop read doc.txt ?
Request allowed
Here's the doc...

Availability and Pricing
Amazon Verified Permissions is available today in all commercial AWS Regions, excluding those that are based in China.

With Amazon Verified Permissions, you only pay for what you use based on the number of authorization requests and API calls made to the service.

Using Amazon Verified Permissions, you can configure fine-grained permissions using the Cedar policy language and simplify the code of your applications. In this way, permissions are maintained in a centralized store and are easier to audit. Here, you can read more about how we built Cedar with automated reasoning and differential testing.

Manage authorization for your applications with Amazon Verified Permissions.

— Danilo

AWS Week in Review – Automate DLQ Redrive for SQS, Lambda Supports Ruby 3.2, and More – June 12, 2023

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/aws-week-in-review-automate-dlq-redrive-for-sqs-lambda-supports-ruby-3-2-and-more-june-12-2023/

Today I’m boarding a plane for Madrid. I will attend the AWS Summit Madrid this Thursday, and I will take Serverlesspresso with me. Serverlesspresso is a demo that we take to events, in where you can learn how to build event-driven architectures with serverless. If you are visiting an AWS Summit, most probably you will find one of our booths.

Serverlesspresso at Madrid

Last Week’s Launches
Here are some launches that got my attention during the previous week.

Amazon SQS – Customers were very excited when we announced the DLQ redrive for Amazon SQS as that feature helped them to easily redirect the failed messages. This week we added support for AWS SDK and CLI for this feature, allowing you to redrive the messages on the DLQ automatically, making it even easier to use this feature. You can read Seb’s blog post about this new feature to learn how to get started.

AWS Lambda – AWS Lambda now supports Ruby 3.2. Ruby 3.2 has many new improvements, for example, passing anonymous arguments to functions or having endless methods. Check out this blog post that goes in depth into each of the new features.

Amazon Fraud Detector – Amazon Fraud Detector supports event orchestration with Amazon EventBridge. This is a very important feature because now you can act on the different events that Fraud Detector emits, for example, send notifications to different stakeholders.

AWS Glue – This week, AWS Glue made two important announcements. First, it announced the general availability of AWS Glue for Ray, a new data integration engine option for AWS Glue. Ray is a popular new open-source compute framework that helps developers to scale their Python workloads. In addition, AWS Glue announced AWS Glue Data Quality, a new capability that automatically measures and monitors data lake and data pipeline quality.

Amazon Elastic Container Registry (Amazon ECR) – AWS Signer and Amazon ECR announced a new feature that allows you to sign and verify container images. You can use Signer to validate that only container images you have approved are deployed in your Amazon Elastic Kubernetes Service (Amazon EKS) clusters.

Amazon QuickSight – Amazon QuickSight now supports APIs to automate asset deployment, so you can replicate the same QuickSight assets in multiple Regions and account easily. You can read more on how to use those APIs in this blog post.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Some other updates and news that you may have missed:

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

  • AWS Silicon Innovation Day (June 21) – A one-day virtual event that focuses on AWS Silicon and how you can take advantage of AWS’s unique offerings. Learn more and register here.
  • AWS Global Summits – There are many summits going on right now around the world: Toronto (June 14), Madrid (June 15), and Milano (June 22).
  • AWS Community Day – Join a community-led conference run by AWS user group leaders in your region: Chicago (June 15), Manila (June 29–30), Chile (July 1), and Munich (September 14).
  • CDK Day – CDK Day is happening again this year on September 29. The call for papers for this event is open, and this year we are also accepting talks in Spanish. Submit your talk here.

That’s all for this week. Check back next Monday for another Week in Review!

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

— Marcia

New – Move Payment Processing to the Cloud with AWS Payment Cryptography

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-move-payment-processing-to-the-cloud-with-aws-payment-cryptography/

Cryptography is everywhere in our daily lives. If you’re reading this blog, you’re using HTTPS, an extension of HTTP that uses encryption to secure communications. On AWS, multiple services and capabilities help you manage keys and encryption, such as:

HSMs are physical devices that securely protect cryptographic operations and the keys used by these operations. HSMs can help you meet your corporate, contractual, and regulatory compliance requirements. With CloudHSM, you have access to general-purpose HSMs. When payments are involved, there are specific payment HSMs that offer capabilities such as generating and validating the personal identification number (PIN) and the security code of a credit or debit card.

Today, I am happy to share the availability of AWS Payment Cryptography, an elastic service that manages payment HSMs and keys for payment processing applications in the cloud.

Applications using payments HSMs have challenging requirements because payment processing is complex, time sensitive, and highly regulated and requires the interaction of multiple financial service providers and payment networks. Every time you make a payment, data is exchanged between two or more financial service providers and must be decrypted, transformed, and encrypted again with a unique key at each step.

This process requires highly performant cryptography capabilities and key management procedures between each payment service provider. These providers might have thousands of keys to protect, manage, rotate, and audit, making the overall process expensive and difficult to scale. To add to that, payment HSMs historically employ complex and error-prone processes, such as exchanging keys in a secure room using multiple hand-carried paper forms, each with separate key components printed on them.

Introducing AWS Payment Cryptography
AWS Payment Cryptography simplifies your implementation of cryptographic functions and key management used to secure data in payment processing in accordance with various payment card industry (PCI) standards.

With AWS Payment Cryptography, you can eliminate the need to provision and manage on-premises payment HSMs and use the provided tools to avoid error-prone key exchange processes. For example, with AWS Payment Cryptography, payment and financial service providers can begin development within minutes and plan to exchange keys electronically, eliminating manual processes.

To provide its elastic cryptographic capabilities in a compliant manner, AWS Payment Cryptography uses HSMs with PCI PTS HSM device approval. These capabilities include encryption and decryption of card data, key creation, and pin translation. AWS Payment Cryptography is also designed in accordance with PCI security standards such as PCI DSS, PCI PIN, and PCI P2PE, and it provides evidence and reporting to help meet your compliance needs.

You can import and export symmetric keys between AWS Payment Cryptography and on-premises HSMs under key encryption key (KEKs) using the ANSI X9 TR-31 protocol. You can also import and export symmetric KEKs with other systems and devices using the ANSI X9 TR-34 protocol, which allows the service to exchange symmetric keys using asymmetric techniques.

To simplify moving consumer payment processing to the cloud, existing card payment applications can use AWS Payment Cryptography through the AWS SDKs. In this way, you can use your favorite programming language, such as Java or Python, instead of vendor-specific ASCII interfaces over TCP sockets, as is common with payment HSMs.

Access can be authorized using AWS Identity and Access Management (IAM) identity-based policies, where you can specify which actions and resources are allowed or denied and under which conditions.

Monitoring is important to maintain the reliability, availability, and performance needed by payment processing. With AWS Payment Cryptography, you can use Amazon CloudWatch, AWS CloudTrail, and Amazon EventBridge to understand what is happening, report when something is wrong, and take automatic actions when appropriate.

Let’s see how this works in practice.

Using AWS Payment Cryptography
Using the AWS Command Line Interface (AWS CLI), I create a double-length 3DES key to be used as a card verification key (CVK). A CVK is a key used for generating and verifying card security codes such as CVV, CVV2, and similar values.

Note that there are two commands for the CLI (and similarly two endpoints for API and SDKs):

  • payment-cryptography for control plane operation such as listing and creating keys and aliases.
  • payment-cryptography-data for cryptographic operations that use keys, for example, to generate PIN or card validation data.

Creating a key is a control plane operation:

aws payment-cryptography create-key \
    --no-exportable \
    --key-attributes KeyAlgorithm=TDES_2KEY,
                     KeyUsage=TR31_C0_CARD_VERIFICATION_KEY,
                     KeyClass=SYMMETRIC_KEY,
                     KeyModesOfUse='{Generate=true,Verify=true}'
{
    "Key": {
        "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h",
        "KeyAttributes": {
            "KeyUsage": "TR31_C0_CARD_VERIFICATION_KEY",
            "KeyClass": "SYMMETRIC_KEY",
            "KeyAlgorithm": "TDES_2KEY",
            "KeyModesOfUse": {
                "Encrypt": false,
                "Decrypt": false,
                "Wrap": false,
                "Unwrap": false,
                "Generate": true,
                "Sign": false,
                "Verify": true,
                "DeriveKey": false,
                "NoRestrictions": false
            }
        },
        "KeyCheckValue": "B2DD4E",
        "KeyCheckValueAlgorithm": "ANSI_X9_24",
        "Enabled": true,
        "Exportable": false,
        "KeyState": "CREATE_COMPLETE",
        "KeyOrigin": "AWS_PAYMENT_CRYPTOGRAPHY",
        "CreateTimestamp": "2023-05-26T14:25:48.240000+01:00",
        "UsageStartTimestamp": "2023-05-26T14:25:48.220000+01:00"
    }
}

To reference this key in the next steps, I can use the Amazon Resource Name (ARN) as found in the KeyARN property, or I can create an alias. An alias is a friendly name that lets me refer to a key without having to use the full ARN. I can update an alias to refer to a different key. When I need to replace a key, I can just update the alias without having to change the configuration or the code of your applications. To be recognized easily, alias names start with alias/. For example, the following command creates the alias alias/my-key for the key I just created:

aws payment-cryptography create-alias --alias-name alias/my-key \
    --key-arn arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h
{
    "Alias": {
        "AliasName": "alias/my-key",
        "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h"
    }
}

Before I start using the new key, I list all my keys to check their status:

aws payment-cryptography list-keys
{
    "Keys": [
        {
            "KeyArn": "arn:aws:payment-cryptography:us-west-2:123421341234:key/42cdc4ocf45mg54h",
            "KeyAttributes": {
                "KeyUsage": "TR31_C0_CARD_VERIFICATION_KEY",
                "KeyClass": "SYMMETRIC_KEY",
                "KeyAlgorithm": "TDES_2KEY",
                "KeyModesOfUse": {
                    "Encrypt": false,
                    "Decrypt": false,
                    "Wrap": false,
                    "Unwrap": false,
                    "Generate": true,
                    "Sign": false,
                    "Verify": true,
                    "DeriveKey": false,
                    "NoRestrictions": false
                }
            },
            "KeyCheckValue": "B2DD4E",
            "Enabled": true,
            "Exportable": false,
            "KeyState": "CREATE_COMPLETE"
        },
        {
            "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/ok4oliaxyxbjuibp",
            "KeyAttributes": {
                "KeyUsage": "TR31_C0_CARD_VERIFICATION_KEY",
                "KeyClass": "SYMMETRIC_KEY",
                "KeyAlgorithm": "TDES_2KEY",
                "KeyModesOfUse": {
                    "Encrypt": false,
                    "Decrypt": false,
                    "Wrap": false,
                    "Unwrap": false,
                    "Generate": true,
                    "Sign": false,
                    "Verify": true,
                    "DeriveKey": false,
                    "NoRestrictions": false
                }
            },
            "KeyCheckValue": "905848",
            "Enabled": true,
            "Exportable": false,
            "KeyState": "DELETE_PENDING"
        }
    ]
}

As you can see, there is another key I created before, which has since been deleted. When a key is deleted, it is marked for deletion (DELETE_PENDING). The actual deletion happens after a configurable period (by default, 7 days). This is a safety mechanism to prevent the accidental or malicious deletion of a key. Keys marked for deletion are not available for use but can be restored.

In a similar way, I list all my aliases to see to which keys they are they referring:

aws payment-cryptography list-aliases
{
    "Aliases": [
        {
            "AliasName": "alias/my-key",
            "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h"
        }
    ]
}

Now, I use the key to generate a card security code with the CVV2 authentication system. You might be familiar with CVV2 numbers that are usually written on the back of a credit card. This is the way they are computed. I provide as input the primary account number of the credit card, the card expiration date, and the key from the previous step. To specify the key, I use its alias. This is a data plane operation:

aws payment-cryptography-data generate-card-validation-data \
    --key-identifier alias/my-key \
    --primary-account-number=171234567890123 \
    --generation-attributes CardVerificationValue2={CardExpiryDate=0124}
{
    "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h",
    "KeyCheckValue": "B2DD4E",
    "ValidationData": "343"
}

I take note of the three digits in the ValidationData property. When processing a payment, I can verify that the card data value is correct:

aws payment-cryptography-data verify-card-validation-data \
    --key-identifier alias/my-key \
    --primary-account-number=171234567890123 \
    --verification-attributes CardVerificationValue2={CardExpiryDate=0124} \
    --validation-data 343
{
    "KeyArn": "arn:aws:payment-cryptography:us-west-2:123412341234:key/42cdc4ocf45mg54h",
    "KeyCheckValue": "B2DD4E"
}

The verification is successful, and in return I get back the same KeyCheckValue as when I generated the validation data.

As you might expect, if I use the wrong validation data, the verification is not successful, and I get back an error:

aws payment-cryptography-data verify-card-validation-data \
    --key-identifier alias/my-key \
    --primary-account-number=171234567890123 \
    --verification-attributes CardVerificationValue2={CardExpiryDate=0124} \
    --validation-data 999

An error occurred (com.amazonaws.paymentcryptography.exception#VerificationFailedException)
when calling the VerifyCardValidationData operation:
Card validation data verification failed

In the AWS Payment Cryptography console, I choose View Keys to see the list of keys.

Console screenshot.

Optionally, I can enable more columns, for example, to see the key type (symmetric/asymmetric) and the algorithm used.

Console screenshot.

I choose the key I used in the previous example to get more details. Here, I see the cryptographic configuration, the tags assigned to the key, and the aliases that refer to this key.

Console screenshot.

AWS Payment Cryptography supports many more operations than the ones I showed here. For this walkthrough, I used the AWS CLI. In your applications, you can use AWS Payment Cryptography through any of the AWS SDKs.

Availability and Pricing
AWS Payment Cryptography is available today in the following AWS Regions: US East (N. Virginia) and US West (Oregon).

With AWS Payment Cryptography, you only pay for what you use based on the number of active keys and API calls with no up-front commitment or minimum fee. For more information, see AWS Payment Cryptography pricing.

AWS Payment Cryptography removes your dependencies on dedicated payment HSMs and legacy key management systems, simplifying your integration with AWS native APIs. In addition, by operating the entire payment application in the cloud, you can minimize round-trip communications and latency.

Move your payment processing applications to the cloud with AWS Payment Cryptography.

— Danilo

Announcing the latest AWS Heroes – June 2023

Post Syndicated from Taylor Jacobsen original https://aws.amazon.com/blogs/aws/announcing-the-latest-aws-heroes-june-2023/

AWS Heroes dedicate their time to help others build better and faster on AWS. Heroes support and give back to the community in a variety of ways: contributing to open source projects, organizing AWS Community Days, speaking at conferences, leading workshops, mentoring builders, hosting meetups, and much more.

Please welcome and say hello to our newest AWS Heroes!

AJ Stuyvenberg – Boston, USA

Serverless Hero AJ Stuyvenberg is a Staff Engineer at Datadog, and has been a member of the serverless community since early 2017. His work focuses on serverless and distributed system observability. AJ is an open source author and maintains several projects, which improve the serverless developer experience. He has also spoken at multiple conferences, including AWS re:Invent and AWS Summits, and frequently writes about serverless topics on his blog.

Danielle Heberling – Hillsboro, USA

Serverless Hero Danielle Heberling is a software engineer with a background that includes being a musician, teaching at a K-8 public school, and working in technical support. She’s passionate about building things that make the world a better place, whether that be through social change or a good laugh. When she’s not coding or talking about serverless, you can often find her reaching back to her teaching roots by mentoring folks from underrepresented groups that would like to make a career switch into tech.

Dominik Grzywaczewski – Lublin, Poland

Community Hero Dominik Grzywaczewski is a Senior Cloud Site Reliability Engineer at Chaos Gears with more than 15 years of experience in IT. His primary objective is to assist companies in gaining a deeper understanding of Cloud Computing technologies, and effectively leveraging them to drive faster and more secure innovation. Dominik shares his passion by organizing technical meetups and workshops, and consistently collaborates with AWS community members. He also founded the AWS User Group in Lublin (Poland) and co-organizes the AWS Community Day conference in Warsaw (Poland).

Johannes Koch – Hessen, Germany

DevTools Hero Johannes Koch is a Sr. DevOps Engineer, Developer Experience, GTS at FICO where he contributes to the FICO®️ Platform. He shares his best practices related to Continuous Integration and Continuous Deployment (CI/CD) on his YouTube channel: cicdonaws. Johannes also founded the AWS User Group Bergstrasse, helped to start the AWS Community DACH Förderverein, and is part of the team that organizes the AWS Community Day in the DACH region.

Michael Walmsley – Melbourne, Australia

Serverless Hero Michael Walmsley is a Lead Technology Architect in the myWizard®️ Automation Group at Accenture, where he is focused on building event-driven products in the cloud. He is excited by the AWS Lambda Powertools open-source projects, and has been using and actively contributing to them since 2020. Michael is also a passionate AWS community member in Australia, supporting local meetups and conferences. He helps organize and run the AWS Programming and Tools Meetup in Melbourne, which focuses on running monthly hands-on training workshops that are open to everyone.

Mikey Fan – Beijing, China

Community Hero Mikey Fan is a Cloud-native Application Architect and SDN Developer. Since 2020, he has been actively exploring how to build innovative applications based on AWS EKS, Private 5G, and SD-WAN technology, and then applying them to 5G Edge Computing scenarios. Mikey is also a cloud-computing technology evangelist and an open-source enthusiast. He enjoys contributing code to open-source projects, such as Kubernetes and Tungsten Fabric, and he likes to demo how these open-source technologies can be combined with AWS cloud computing to create greater value.

Ran Isenberg – Kfar Saba, Israel

Serverless Hero Ran Isenberg is a principal software architect at CyberArk, where he designs and builds serverless services. He is passionate about CI/CD and AWS CDK, and has contributed several utilities to the AWS Lambda Powertools open-source project. Ran also maintains numerous serverless related open-source projects on his GitHub account, such as the AWS Lambda cookbook – a serverless service template that gets you started in the serverless world with all of the best practices in seconds.

Sabiha Ali – Dubai, United Arab Emirates

Community Hero Sabiha Ali is a Solutions Architect at ScaleCapacity. She specializes in Amazon Connect, architecting resilient and secure systems in the cloud. As an Amazon Connect Ambassador, she helps businesses enhance their customer experiences. Her unwavering passion for learning has earned her numerous AWS certifications (9X), solidifying her expertise in the field. She became an AWS User Group Leader in Dubai after starting out as an active AWS Community Builder. Sabiha is also committed to empowering women in the tech industry, making her a valued professional and an advocate for change.

Tomasz Dudek – Wroclaw, Poland

Machine Learning Hero Tomasz Dudek works as a Data & AI Team Lead and a Solutions Architect at Chaos Gears. He guides customers on how leveraging machine learning powered solutions can help their businesses thrive. He also designs AWS architectures and manages a data-focused team. Additionally, Tomasz co-organizes the AWS Community Day Poland, and as well as hosts the AWS User Group in his hometown Wroclaw. He often conducts workshops, such as SageMaker Immersion Days, speaks at conferences, and shares his knowledge in the form of short posts on LinkedIn, and longer ones on his blog, ‘MLOps and how you tame it.’

Wojciech Dąbrowski – Katowice, Poland

Community Hero Wojciech Dąbrowski is Head of Cloud Architecture at DTiQ, where he leads the team responsible for the architecture of cloud solutions and the cloud adaptation strategy in the organization. He has been an AWS User Group Silesia leader since 2019, and has managed to organize multiple online and offline meetups. In addition, Wojciech leads workshops and presents cloud computing and software engineering topics at various events.

Learn More

If you’d like to learn more about the new Heroes or connect with a Hero near you, please visit the AWS Heroes website or browse the AWS Heroes Content Library.

— Taylor

A New Set of APIs for Amazon SQS Dead-Letter Queue Redrive

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/a-new-set-of-apis-for-amazon-sqs-dead-letter-queue-redrive/

Today, we launch a new set of APIs for Amazon Simple Queue Service (Amazon SQS). These new APIs allow you to manage dead-letter queue (DLQ) redrive programmatically. You can now use the AWS SDKs or the AWS Command Line Interface (AWS CLI) to programmatically move messages from the DLQ to their original queue, or to a custom queue destination, to attempt to process them again. A DLQ is a queue where Amazon SQS automatically moves messages that are not correctly processed by your consumer application.

To fully appreciate how this new API might help you, let’s have a quick look back at history.

Message queues are an integral part of modern application architectures. They allow developers to decouple services by allowing asynchronous and message-based communications between message producers and consumers. In most systems, messages are persisted in shared storage (the queue) until the consumer processes them. Message queues allow developers to build applications that are resilient to temporary service failure. They help prioritize message processing and scale their fleet of worker nodes that process the messages. Message queues are also popular in event-driven architectures.

Asynchronous message exchange is not new in application architectures. The concept of exchanging messages asynchronously between applications appeared in the 1960s and was first made popular when IBM launched TCAM for OS/360 in 1972. The general adoption came 20 years later with IBM MQ Series in 1993 (now IBM MQ) and when Sun Microsystems released Java Messaging Service (JMS) in 1998, a standard API for Java applications to interact with message queues.

AWS launched Amazon SQS on July 12, 2006. Amazon SQS is a highly scalable, reliable, and elastic queuing service that “just works.” As Werner wrote at the time: “We have chosen a concurrency model where the process working on a message automatically acquires a leased lock on that message; if the message is not deleted before the lease expires, it becomes available for processing again. Makes failure handling very simple.”

On January 29, 2014, we introduced dead-letter queues (DLQ). DLQs help you avoid a message that failed to be processed from staying forever on top of the queue, possibly preventing other messages in the queue from processing. With DLQs, each queue has an associated property telling Amazon SQS how many times a message may be presented for processing (maxReceiveCount). Each message also has an associated receive counter (ReceiveCount). Each time a consumer application picks up a message for processing, the message receive count is incremented by 1. When ReceiveCount > maxReceiveCount, Amazon SQS moves the message to your designated DLQ for human analysis and debugging. You generally associate alarms with the DLQ to send notifications when such events happen. Typical reasons to move a message to the DLQ are because they are incorrectly formatted, there are bugs in the consumer application, or it takes too long to process the message.

At AWS re:Invent 2021, AWS announced dead-letter queue redrive on the Amazon SQS console. The redrive addresses the second part of the failed message lifecycle. It allows you to reinject the message in its original queue to attempt processing it again. After the consumer application is fixed and ready to consume the failed messages, you can redrive the messages from the DLQ back in the source queue or a customized queue destination. It just requires a couple of clicks on the console.

Today, we are adding APIs allowing you to write applications and scripts that handle the redrive programmatically. There is no longer a need to have a human clicking on the console. Using the API increases the scalability of your processes and reduces the risk of human error.

Let’s See It in Action
To try out this new API, I open a terminal for a command-line only demo. Before I get started, I make sure I have the latest version of the AWS CLI. On macOS I enter brew upgrade awscli.

I first create two queues. One is the dead-letter queue, and the other is my application queue:

# First, I create the dead-letter queue (notice the -dlq I choose to add at the end of the queue name)
➜ ~ aws sqs create-queue \
            --queue-name awsnewsblog-dlq                                            
{
    "QueueUrl": "https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog-dlq"
}

# second, I retrieve the Arn of the queue I just created
➜  ~ aws sqs get-queue-attributes \
             --queue-url https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog-dlq \
             --attribute-names QueueArn
{
    "Attributes": {
        "QueueArn": "arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq"
    }
}

# Third, I create the application queue. I enter a redrive policy: post messages in the DLQ after three delivery attempts
➜  ~ aws sqs create-queue \
             --queue-name awsnewsblog \
             --attributes '{"RedrivePolicy": "{\"deadLetterTargetArn\":\"arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq\",\"maxReceiveCount\":\"3\"}"}' 
{
    "QueueUrl": "https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog"
}

Now that the two queues are ready, I post a message to the application queue:

➜ ~ aws sqs send-message \
            --queue-url https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog \
            --message-body "Hello World"
{
"MD5OfMessageBody": "b10a8db164e0754105b7a99be72e3fe5",
"MessageId": "fdc26778-ce9a-4782-9e33-ae73877cfcb2"
}

Next, I consume the message, but I don’t delete it from the queue. This simulates a crash in the message consumer application. Message consumers are supposed to delete the message after successful processing. I set the maxReceivedCount property to 3 when I entered the redrivePolicy. I therefore repeat this operation three times to force Amazon SQS to move the message to the dead-letter queue after three delivery attempts. The default visibility timeout is 30 seconds, so I have to wait 30 seconds or more between the retries.

➜ ~ aws sqs receive-message \
            --queue-url https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog
{
"Messages": [
{
"MessageId": "fdc26778-ce9a-4782-9e33-ae73877cfcb2",
"ReceiptHandle": "AQEBP8yOfgBlnjlkGXjyeLROiY7xg7cZ6Znq8Aoa0d3Ar4uvTLPrHZptNotNfKRK25xm+IU8ebD3kDwZ9lja6JYs/t1kBlwiNO6TBACN5srAb/WggQiAAkYl045Tx3CvsOypbJA3y8U+MyEOQRwIz6G85i7MnR8RgKTlhOzOZOVACXC4W8J9GADaQquFaS1wVeM9VDsOxds1hDZLL0j33PIAkIrG016LOQ4sAntH0DOlEKIWZjvZIQGdlRJS65PJu+I/Ka1UPHGiFt9f8m3SR+Y34/ttRWpQANlXQi5ByA47N8UfcpFXXB5L30cUmoDtKucPewsJNG2zRCteR0bQczMMAmOPujsKq70UGOT8X2gEv2LfhlY7+5n8z3yew8sdBjWhVSegrgj6Yzwoc4kXiMddMg==",
"MD5OfBody": "b10a8db164e0754105b7a99be72e3fe5",
"Body": "Hello World"
}
]
}

# wait 30 seconds,
# then repeat two times (for a total of three receive-message API calls)

After three processing attempts, the message is not in the queue anymore:

➜  ~ aws sqs receive-message \
             --queue-url  https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog
{
    "Messages": []
}

The message has been moved to the dead-letter queue. I check the DLQ to confirm (notice the queue URL ending with -dlq):

➜  ~ aws sqs receive-message \
             --queue-url  https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog-dlq
{
    "Messages": [
        {
            "MessageId": "fdc26778-ce9a-4782-9e33-ae73877cfcb2",
            "ReceiptHandle": "AQEBCLtBMoZYVMMq7fUGNHeCliqE3mFXnkuJ+nOXLK1++uoXWBG31nDejCpxElmiBZWfbcfGJrEdKj4P9HJdrQMYDbeSqB+u1ZlB7CYzQBiQps4SEG0biEoubwqjQbmDZlPrmkFsnYgLD98D1XYWk/Ik6Z2n/wxDo9ko9rbZ15izK5RFnbwveNy8dfc6ireqVB1EGbeGkHcweHGuoeKWXEab1ynZWhNqZsQgCR6pWRkgtn59lJcLv4cJ4UMewNzvt7tMHH69GvVjXdYDYvJJI2vj+6RHvcvSHWWhTNT+CuPEXguVNuNrSya8gho1fCnKpVwQre6HhMlLPjY4wvn/tXY7+5rmte9eXagCqLQXaENB2R7qWNVPiWRIJy8/cTf37NLYVzBom030DNJlH9EeceRhCQ==",
            "MD5OfBody": "b10a8db164e0754105b7a99be72e3fe5",
            "Body": "Hello World"
        }
    ]
}

Now that the setup is ready, let’s programmatically redrive the message to its original queue. Let’s assume I understand why the consumer didn’t correctly process the message and that I fixed the consumer application code. I use start-message-move-task on the DLQ to start the asynchronous redrive. There is an optional attribute (MaxNumberOfMessagesPerSecond) to control the velocity of the redrive:

➜ ~ aws sqs start-message-move-task \
            --source-arn arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq
{
    "TaskHandle": "eyJ0YXNrSWQiOiI4ZGJmNjBiMy00MmUwLTQzYTYtYjg4Zi1iMTZjYWRjY2FkNmEiLCJzb3VyY2VBcm4iOiJhcm46YXdzOnNxczp1cy1lYXN0LTI6NDg2NjUyMDY2NjkzOmF3c25ld3NibG9nLWRscSJ9"
}

I can list and check status the of the move tasks I initiated with list-message-move-tasks or cancel a running task by calling the cancel-message-move-task API:

➜ ~ aws sqs list-message-move-tasks \
            --source-arn arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq
{
    "Results": [
        {
            "Status": "COMPLETED",
            "SourceArn": "arn:aws:sqs:us-east-2:012345678900:awsnewsblog-dlq",
            "ApproximateNumberOfMessagesMoved": 1,
            "ApproximateNumberOfMessagesToMove": 1,
            "StartedTimestamp": 1684135792239
        }
    ]
}

Now my application can consume the message again from the application queue:

➜  ~ aws sqs receive-message \
             --queue-url  https://sqs.us-east-2.amazonaws.com/012345678900/awsnewsblog                                   
{
    "Messages": [
        {
            "MessageId": "a7ae83ca-cde4-48bf-b822-3d4bc1f4dcae",
            "ReceiptHandle": "AQEB9a+Dm2nvb3VUn9+46j9UsDidU/W6qFwJtXtNWTyfoSDOKT7h73e6ctT9RVZysEw3qqzJOx1cxblTTOSrYwwwoBA2qoJMGsqsrsRGGYojBvf9X8hqi8B8MHn9rTm8diJ2wT2b7WC+TDrx3zIvUeiSEkP+EhqyYOvOs7Q9aETR+Uz02kQxZ/cUJWsN4MMSXBejwW+c5ivv5uQtpfUrfZuCWa9B9O67Kj/q52clriPHpcqCCfJwFBSZkGTXYwTpnjxD4QM7DPS+xVeVfTyM7DsKCAOtpvFBmX5m4UNKT6TROgCnGxTRglUSMWQp8ufVxXiaUyM1dwqxYekM9uX/RCb01gEyCZHas4jeNRV5nUJlhBkkqPlw3i6w9Uuc2y9nH0Df8nH3g7KTXo4lv5Bl3ayh9w==",
            "MD5OfBody": "b10a8db164e0754105b7a99be72e3fe5",
            "Body": "Hello World"
        }
    ]
}

Availability
DLQ redrive APIs are available today in all commercial Regions where Amazon SQS is available.

Redriving the messages from the dead-letter queue to the source queue or a custom destination queue generates additional API calls billed based on existing pricing (starting at $0.40 per million API calls, after the first million, which is free every month). Amazon SQS batches the messages while redriving them from one queue to another. This makes moving messages from one queue to another a simple and low-cost option.

To learn more about DLQ and DLQ redrive, check our documentation.

Remember that we live in an asynchronous world—so should your applications. Get started today and write your first redrive application.

— seb

2023 ISO and CSA STAR certificates now available with 8 new services and 1 new Region

Post Syndicated from Atul Patil original https://aws.amazon.com/blogs/security/2023-iso-and-csa-star-certificates-now-available-with-8-new-services-and-1-new-region/

Amazon Web Services (AWS) successfully completed a special onboarding audit with no findings for ISO 9001, 27001, 27017, 27018, 27701, and 22301, and Cloud Security Alliance (CSA) STAR CCM v4.0. Ernst and Young Certify Point auditors conducted the audit and reissued the certificates on May 23, 2023. The objective of the audit was to assess the level of compliance with the requirements of the applicable international standards.

We added eight additional AWS services and one additional AWS Region to the scope of this special onboarding audit. The following are the eight additional services:

The additional Region is Asia Pacific (Melbourne).

For a full list of AWS services that are certified under ISO and CSA Star, see the AWS ISO and CSA STAR Certified page. Customers can also access the certifications in the console through AWS Artifact.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Atul Patil

Atul Patil

Atul is a Compliance Program Manager at AWS. He has 27 years of consulting experience in information technology and information security management. Atul holds a Master’s degree in electronics, and professional certifications such as CCSP, CISSP, CISM, ISO 27001 Lead Auditor, HITRUST CSF, Archer Certified Consultant, and AWS CCP certifications.

Mary Roberts

Mary Roberts

Mary is a Compliance Program Manager at AWS. She is a cybersecurity leader, and an adjunct professor with several years of experience leading and teaching cybersecurity, security governance, risk management, and compliance. Mary holds a Master’s degree in cybersecurity and information assurance, and industry certifications such as CISSP, CHFI, CEH, ISO 27001 Lead Auditor, and AWS Solutions Architect.

Nimesh Ravas

Nimesh Ravasa

Nimesh is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Nimesh has 15 years of experience in information security and holds CISSP, CISA, PMP, CSX, AWS Solutions Architect – Associate, and AWS Security Specialty certifications.

Our commitment to shared cybersecurity goals

Post Syndicated from Mark Ryland original https://aws.amazon.com/blogs/security/our-commitment-to-shared-cybersecurity-goals/

The United States Government recently launched its National Cybersecurity Strategy. The Strategy outlines the administration’s ambitious vision for building a more resilient future, both in the United States and around the world, and it affirms the key role cloud computing plays in realizing this vision.

Amazon Web Services (AWS) is broadly committed to working with customers, partners, and governments such as the United States to improve cybersecurity. That longstanding commitment aligns with the goals of the National Cybersecurity Strategy. In this blog post, we will summarize the Strategy and explain how AWS will help to realize its vision.

The Strategy identifies two fundamental shifts in how the United States allocates cybersecurity roles, responsibilities, and resources. First, the Strategy calls for a shift in cybersecurity responsibility away from individuals and organizations with fewer resources, toward larger technology providers that are the most capable and best-positioned to be successful. At AWS, we recognize that our success and scale bring broad responsibility. We are committed to improving cybersecurity outcomes for our customers, our partners, and the world at large.

Second, the Strategy calls for realigning incentives to favor long-term investments in a resilient future. As part of our culture of ownership, we are long-term thinkers, and we don’t sacrifice long-term value for short-term results. For more than fifteen years, AWS has delivered security, identity, and compliance services for millions of active customers around the world. We recognize that we operate in a complicated global landscape and dynamic threat environment that necessitates a dynamic approach to security. Innovation and long-term investments have been and will continue to be at the core of our approach, and we continue to innovate to build and improve on our security and the services we offer customers.

AWS is working to enhance cybersecurity outcomes in ways that align with each of the Strategy’s five pillars:

  1. Defend Critical Infrastructure — Customers, partners, and governments need confidence that they are migrating to and building on a secure cloud foundation. AWS is architected to have the most flexible and secure cloud infrastructure available today, and our customers benefit from the data centers, networks, custom hardware, and secure software layers that we have built to satisfy the requirements of the most security-sensitive organizations. Our cloud infrastructure is secure by design and secure by default, and our infrastructure and services meet the high bar that the United States Government and other customers set for security.
  2. Disrupt and Dismantle Threat Actors — At AWS, our paramount focus on security leads us to implement important measures to prevent abuse of our services and products. Some of the measures we undertake to deter, detect, mitigate, and prevent abuse of AWS products include examining new registrations for potential fraud or identity falsification, employing service-level containment strategies when we detect unusual behavior, and helping protect critical systems and sensitive data against ransomware. Amazon is also working with government to address these threats, including by serving as one of the first members of the Joint Cyber Defense Collaborative (JCDC). Amazon is also co-leading a study with the President’s National Security Telecommunications Advisory Committee on addressing the abuse of domestic infrastructure by foreign malicious actors.
  3. Shape Market Forces to Drive Security and Resilience — At AWS, security is our top priority. We continuously innovate based on customer feedback, which helps customer organizations to accelerate their pace of innovation while integrating top-tier security architecture into the core of their business and operations. For example, AWS co-founded the Open Cybersecurity Schema Framework (OCSF) project, which facilitates interoperability and data normalization between security products. We are contributing to the quality and safety of open-source software both by direct contributions to open-source projects and also by an initial commitment of $10 million in a variety of open-source security improvement projects in and through the Open Source Security Foundation (OpenSSF).
  4. Invest in a Resilient Future — Cybersecurity skills training, workforce development, and education on next-generation technologies are essential to addressing cybersecurity challenges. That’s why we are making significant investments to help make it simpler for people to gain the skills they need to grow their careers, including in cybersecurity. Amazon is committing more than $1.2 billion to provide no-cost education and skills training opportunities to more than 300,000 of our own employees in the United States, to help them secure new, high-growth jobs. Amazon is also investing hundreds of millions of dollars to provide no-cost cloud computing skills training to 29 million people around the world. We will continue to partner with the Cybersecurity and Infrastructure Security Agency (CISA) and others in government to develop the cybersecurity workforce.
  5. Forge International Partnerships to Pursue Shared Goals — AWS is working with governments around the world to provide innovative solutions that advance shared goals such as bolstering cyberdefenses and combating security risks. For example, we are supporting international forums such as the Organization of American States to build security capacity across the hemisphere. We encourage the administration to look toward internationally recognized, risk-based cybersecurity frameworks and standards to strengthen consistency and continuity of security among interconnected sectors and throughout global supply chains. Increased adoption of these standards and frameworks, both domestically and internationally, will mitigate cyber risk while facilitating economic growth.

AWS shares the Biden administration’s cybersecurity goals and is committed to partnering with regulators and customers to achieve them. Collaboration between the public sector and industry has been central to US cybersecurity efforts, fueled by the recognition that the owners and operators of technology must play a key role. As the United States Government moves forward with implementation of the National Cybersecurity Strategy, we look forward to redoubling our efforts and welcome continued engagement with all stakeholders—including the United States Government, our international partners, and industry collaborators. Together, we can address the most difficult cybersecurity challenges, enhance security outcomes, and build toward a more secure and resilient future.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Mark Ryland

Mark Ryland

Mark is the director of the Office of the CISO for AWS. He has over 30 years of experience in the technology industry, and has served in leadership roles in cybersecurity, software engineering, distributed systems, technology standardization, and public policy. Previously, he served as the Director of Solution Architecture and Professional Services for the AWS World Public Sector team.

Ruby 3.2 runtime now available in AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/ruby-3-2-runtime-now-available-in-aws-lambda/

This post is written by Praveen Koorse, Senior Solutions Architect, AWS.

AWS Lambda now supports Ruby 3.2 runtime. With this release, Ruby developers can now take advantage of new features and improvements introduced in Ruby 3 when creating serverless applications on Lambda. Use this runtime today by specifying the runtime parameter of ruby3.2 when creating or updating Lambda functions.

Ruby 3.2 adds many features and performance improvements, including anonymous arguments passing improvements, ‘endless’ methods, Regexp improvements, a new Data class, support for pattern-matching in Time and MatchData, and support for ‘find pattern’ in pattern matching.

Our testing shows Ruby 3.2 cold starts are marginally slower than Ruby 2.7 for a trivial ‘hello world’ function. However, for many real-world workloads, the improved execution performance of Ruby 3.2 results in similar or better performance overall.

Existing Lambda customers using the Ruby 2.7 runtime should migrate to the Ruby 3.2 runtime as soon as possible. Even though community support for Ruby 2.7 has ended, Lambda has extended support for the Ruby 2.7 runtime until December 7, 2023 to provide existing Ruby customers with time to transition to Ruby 3.2. Functions using Ruby 2.7 continue to be eligible for technical support and Lambda will continue to apply OS security updates to the runtime until this date.

Anonymous arguments passing improvements

Ruby 3.2 has introduced improvements to how you can pass anonymous arguments, making it easier and cleaner to work with keyword arguments in code. Previously, you could pass anonymous keyword arguments to a method by using the delegation syntax (…) or use Module#ruby2_keywords and delegate *args, &block. This method was not intuitive and lacked clarity when working with multiple arguments.

def foo(...)
  target(...)
end

ruby2_keywords def foo(*args, &block)
  target(*args, &block)
end

Now, if a method declaration includes anonymous positional or keyword arguments, those can be passed to the next method as arguments themselves. The same advantages of anonymous block forwarding apply to rest and keyword rest argument forwarding.

def keywords(**) # accept keyword arguments
  foo(**) # pass them to the next method
end

def positional(*) # accept positional arguments
  bar(*) # pass to the next method
end

def positional_keywords(*, **) # same as ...
  foobar(*, **)
end

Endless methods

Ruby 3 introduced endless methods that enable developers to define methods of exactly one statement with a syntax def method() = statement. The syntax doesn’t need an end and allows methods to be defined as short-cut one liners, making the creation of basic utility methods easier and helping developers write clean code and improve readability and maintainability of code.

def dbg_args(a, b=1, c:, d: 6, &block) = puts("Args passed: #{[a, b, c, d, block.call]}")
dbg_args(0, c: 5) { 7 }
# Prints: Args passed: [0, 1, 5, 6, 7]

def square(x) = x**2
square(100) 
# => 10000

Regexp improvements

Regular expression matching can take an unexpectedly long time. If your code attempts to match a possibly inefficient Regexp against an untrusted input, an attacker may exploit it for efficient denial of service (so-called regular expression DoS, or ReDoS).

Ruby 3.2 introduces two improvements to mitigate this.

The first is an improved Regexp matching algorithm using a cache-based approach that allows most Regexp matching to be completed in linear time, thus significantly improving overall match performance.

As the prior optimization cannot be applied to some regular expressions, such as those using advanced features or working with a huge fixed number of repetitions, a Regexp timeout improvement now allows you to specify a timeout for Regexp operations as a fallback measure.

There are two APIs to set timeout:

  • Timeout.timeout: This is a global configuration and applies to all Regexps in the process.
  • timeout keyword for Regexp.new: This allows you to specify a different timeout setting for some Regexps. If used, it takes precedence over the global configuration.
Regexp.timeout = 2.0 # Global configuration set to two seconds
/^x*y?x*()\1$/ =~ "x" * 45000 + "a"
#=> Regexp::TimeoutError is raised in two seconds

my_long_rexp = Regexp.new('^x*y?x*()\1$', timeout: 4)
my_long_rexp =~ "x" * 45000 + "a"
# Regexp::TimeoutError is raised in four seconds

Data class

Ruby 3.2 introduces a new core class – ‘Data’ – to represent simple value-alike objects. The class is similar to Struct and partially shares the implementation, but is intended to be immutable with a more modern interface.

Once a Data class is defined using Data.define, both positional and keyword arguments can be used while constructing objects.

def handler(event:, context:) 
  employee = Data.define(:firstname, :lastname, :empid, :department)

  emp1 = employee.new('John', 'Doe', 12345, 'Sales')
  emp2 = employee.new(firstname: 'Alice', lastname: 'Doe', empid: 12346, department: 'Marketing')

  # Alternative form to construct an object
  emp3 = employee['Jack', 'Frost', 12354, 'Tech']
  emp4 = employee[firstname: 'Emma', lastname: 'Frost', empid: 12453, department: 'HR']
end

Pattern matching improvements

Pattern matching is a feature allowing deep matching of structured values: checking the structure and binding the matched parts to local variables.

Ruby 3.2 introduces ‘Find pattern’, allowing you to check if the given object has any elements that match a pattern. This pattern is similar to the Array pattern, except that it finds the first match in a given object containing multiple elements.

For example, previously, if you used the following in a Lambda function:

person = {name: "John", children: [{name: "Mark", age: 12}, {name: "Butler", age: 9}], siblings: [{name: "Mary", age: 31}, {name: "Conrad", age: 38}] }

case person
in {name: "John", children: [{name: "Mark", age: age}]}
  p age
end

This wouldn’t match because it does not search for the element in the ‘children’ array. It only matches for an array with a single element named “Mark”.

To find an element in an array with multiple elements, use ‘find pattern’:

case person
in {name: "John", children: [*, {name: "Mark", age: age}, *]}
  p age
end

As part of an effort to make core classes more pattern matching friendly, Ruby 3.2 also introduces the ability to deconstruct keys in Time and MatchData, allowing their use in case/in statements for pattern matching.

# `deconstruct_keys(nil)` provides all available keys:
timestamp = Time.now.deconstruct_keys(nil)

# Usage in pattern-matching:
case timestamp
in year: ...2022
  puts "Last year!"
in year: 2022, month: 1..3
  puts "Last year's first quarter"
in year: 2023, month:, day:
  puts "#{day} of #{month}th month!"
end

Standard Date and DateTime classes also have similar implementations for key deconstruction:

require 'date'
Date.today.deconstruct_keys(nil)
#=> {:year=>2023, :month=>1, :day=>15, :yday=>15, :wday=>0}
DateTime.now.deconstruct_keys(nil)
# => {:year=>2023, :month=>1, :day=>15, :yday=>15, :wday=>0, :hour=>17, :min=>19, :sec=>15, :sec_fraction=>(478525469/500000000), :zone=>"+02:00"}

Pattern matching with MatchData result deconstruction:

case db_connection_string.match(%r{postgres://(\w+):(\w+)@(.+)})
in 'admin', password, server
  # do connection with admin rights
in 'devuser', _, 'dev-server.us-east-1.rds.amazonaws.com'
  # connect to dev server
in user, password, server
  # do regular connection
end

YJIT – Yet Another Ruby JIT

YJIT, a lightweight, minimalistic Ruby JIT compiler built inside CRuby, is now an official part of the Ruby 3.2 runtime. It provides significantly higher performance, but also uses more memory than the Ruby interpreter and is generally suited for Ruby on Rails workloads.

By default, YJIT is not enabled in the Lambda Ruby 3.2 runtime. You can enable it for specific functions by setting the RUBY_YJIT_ENABLE environment variable to 1. Once enabled, you can verify it by printing the result of the RubyVM::YJIT.enabled? method.

puts(RubyVM::YJIT.enabled?())
# => true

Using Ruby 3.2 in Lambda

AWS Cloud Development Kit (AWS CDK):

In AWS CDK, set the runtime attribute to Runtime.RUBY_3_2 when creating the function to use this version. In TypeScript:

import * as cdk from 'aws-cdk-lib';
import * as lambda from 'aws-cdk-lib/aws-lambda';

export class MyCdkStack extends cdk.Stack {

  constructor(scope: cdk.App, id: string, props?: cdk.StackProps) {
    	super(scope, id, props);

new lambda.Function(this, 'Ruby32Lambda', {
  		runtime: lambda.Runtime.RUBY_3_2, //execution environment
  		handler: 'test.handler', //file is “test”, function is “handler”
  	code: lambda.Code.fromAsset('lambda'), //code loaded from “lambda” dir
});
}

AWS Management Console

In the Lambda console, specify a runtime parameter value of Ruby 3.2 when creating or updating a function. The Ruby 3.2 runtime is now available in the Runtime dropdown in the Create function page.

Create function

To update an existing Lambda function to Ruby 3.2, navigate to the function in the Lambda console, then choose Edit in the Runtime settings panel. The new version of Ruby is available in the Runtime dropdown:

Edit runtime settings

AWS Serverless Application Model

In the AWS Serverless Application Model (AWS SAM), set the Runtime attribute to ruby3.2 to use this version in your application deployments:

AWSTemplateFormatVersion: '2010-09-09'
Transform: AWS::Serverless-2016-10-31
Description: AWS Lambda Ruby 3.2 example

Resources:
  Ruby32Lambda:
    Type: AWS::Serverless::Function
    Description: 'Lambda function that uses the Ruby3.2 runtime'
    Properties:
      FunctionName: Ruby32Lambda
      Handler: function.handler
      Runtime: ruby3.2
      CodeUri: src/

Conclusion

Get started building with Ruby 3.2 today by making necessary changes for compatibility with Ruby 3.2, and specifying a runtime parameter value of ruby3.2 when creating or updating your Lambda functions. You can read about the Ruby programming model in the Lambda documentation to learn more about writing functions in Ruby 3.2.

For more serverless learning resources, visit Serverless Land.

Updated AWS Ramp-Up Guide available for security, identity, and compliance

Post Syndicated from Anna McAbee original https://aws.amazon.com/blogs/security/updated-aws-ramp-up-guide-available-for-security-identity-and-compliance/

To support our customers in securing their Amazon Web Services (AWS) environment, AWS offers digital training, whitepapers, blog posts, videos, workshops, and documentation to learn about security in the cloud.

The AWS Ramp-Up Guide: Security is designed to help you quickly learn what is most important to you when it comes to security, identity, and compliance. The Ramp-Up Guide helps you get started with learning cloud foundations and then provides you with options for building skills in various security domains.

Recently, we have updated the AWS Ramp-Up Guide: Security. In this post, we will highlight some of the changes and discuss how to use the new guide.

Update highlights

Based on customer feedback, new service and feature releases, and our experience helping customers, we’ve updated the majority of the guide with new content. Some highlights of the new version include:

  • Focus on AWS security digital trainings — The new Ramp-Up Guide for security focuses on digital trainings provided by AWS Skill Builder. AWS Skill Builder is a learning center for AWS customers and partners to build cloud skills through digital trainings, self-paced labs, and other course types. AWS Skill Builder has a variety of AWS security content to help customers understand concepts and gain hands-on experience with AWS security.
  • Security focus areas — Because there are different roles and focuses within cybersecurity, we created sections for different focus areas of AWS security, including threat detection and incident response (TD/IR), compliance, data protection, and more. A Security Operations Center (SOC) analyst, for example, can choose to focus on TD/IR training, which is most relevant for that role.
  • Extensive additional resources — For each focus area, we added new resources, including whitepapers, blogs, re:Invent videos, and workshops. Customers can use these additional resources to supplement the AWS Skill Builder courses and labs.

How to use the new guide

The AWS Ramp-Up Guide: Security is designed to take you all the way from cloud foundations to the AWS Certified Security – Specialty certification. The guide takes the latest in digital training available from AWS Skill Builder and augments that with the latest resources aligned to foundational concepts and specialized areas within cloud security. Although you are free to use the learnings in any order, if you are new to the cloud, we recommend the following steps:

  1. Sign up for your free AWS Skill Builder account, which provides you with more than 600 digital courses.

    Note: You can optionally buy an AWS Skill Builder subscription if you’d like to complete the self-paced labs. See Pricing options for AWS Skill Builder for more details.

  2. Review the “Learn the fundamentals of the AWS Cloud” section of the Ramp-Up Guide, choose a course name under Learning Resource, and search for that course in Skill Builder. If you are unsure of which course to start with, we recommend that you begin with “AWS Cloud Practitioner Essentials.”
  3. After you’ve completed the “Learn the fundamentals of the AWS Cloud” section, proceed to the “AWS Cloud Security Fundamentals” section begin your security training.
  4. After you complete the Security Fundamentals section, review the specialized security focus areas in the Ramp-Up Guide, choose a focus area, and complete the training items within that focus area.
  5. After you’ve completed the training specific to your focus area, explore other focus areas beyond the scope of your immediate role. Security often requires knowledge across domains and focus areas, so we encourage you to explore the security focus areas beyond the immediate scope of your role.
  6. Review the “Putting it all together” section to prepare for the AWS Certified Security – Specialization certification.
  7. Go build, securely!

More information

For more information and to get started, see the updated AWS Ramp-Up Guide: Security.

We greatly value feedback and contributions from our community. To share your thoughts and insights about the AWS Ramp-Up Guide: Security and your experience using it, and what you want to see in future versions, please contact [email protected].

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Anna McAbee

Anna is a Security Specialist Solutions Architect focused on threat detection and incident response at AWS. Before AWS, she worked as an AWS customer in financial services on both the offensive and defensive sides of security. Outside of work, Anna enjoys cheering on the Florida Gators football team, wine tasting, and traveling the world.

Conor Colgan

Conor Colgan

Conor is a Sr. Solutions Architect on the AWS Healthcare and Life Sciences (HCLS) Startup team. He focuses on helping organizations of all sizes adopt AWS to help meet their business objectives and accelerate their velocity. Prior to AWS, Conor built automated compliance solutions for healthcare customers in the cloud ranging from startups to enterprise, helping them build and demonstrate a culture of compliance.

AWS Glue Data Quality is Generally Available

Post Syndicated from Shiv Narayanan original https://aws.amazon.com/blogs/big-data/aws-glue-data-quality-is-generally-available/

We are excited to announce the General Availability of AWS Glue Data Quality.

Our journey started by working backward from our customers who create, manage, and operate data lakes and data warehouses for analytics and machine learning. To make confident business decisions, the underlying data needs to be accurate and recent. Otherwise, data consumers lose trust in the data and make suboptimal or incorrect decisions. For example, medical researchers found that across 79,000 emergency department encounters of pediatric patients in a hospital, incorrect or missing patient weight measurements led to medication dosing errors in 34% of cases. A data quality check to identify missing patient weight measurements or a check to ensure patients’ weights are trending within certain thresholds would have alerted respective teams to identify these discrepancies.

For our customers, setting up these data quality checks is manual, time consuming, and error prone. It takes days for data engineers to identify and implement data quality rules. They have to gather detailed data statistics, such as minimums, maximums, averages, and correlations. They have to then review the data statistics to identify data quality rules, and write code to implement these checks in their data pipelines. Data engineers must then write code to monitor data pipelines, visualize quality scores, and alert them when anomalies occur. They have to repeat these processes across thousands of datasets and the hundreds of data pipelines populating them. Some customers adopt commercial data quality solutions; however, these solutions require time-consuming infrastructure management and are expensive. Our customers needed a simple, cost-effective, and automatic way to manage data quality.

In this post, we discuss the capabilities and features of AWS Glue Data Quality.

Capabilities of AWS Glue Data Quality

AWS Glue Data Quality accelerates your data quality journey with the following key capabilities:

  • Serverless – AWS Glue Data Quality is a feature of AWS Glue, which eliminates the need for infrastructure management, patching, and maintenance.
  • Reduced manual efforts with recommending data quality rules and out-of-the-box rules – AWS Glue Data Quality computes data statistics such as minimums, maximums, histograms, and correlations for datasets. It then uses these statistics to automatically recommend data quality rules that check for data freshness, accuracy, and integrity. This reduces manual data analysis and rule identification efforts from days to hours. You can then augment recommendations with out-of-the-box data quality rules. The following table lists the rules that are supported by AWS Glue Data Quality as of writing. For an up-to-date list, refer to Data Quality Definition Language (DQDL).
Rule Type Description
AggregateMatch Checks if two datasets match by comparing summary metrics like total sales amount. Useful for customers to compare if all data is ingested from source systems.
ColumnCorrelation Checks how well two columns are corelated.
ColumnCount Checks if any columns are dropped.
ColumnDataType Checks if a column is compliant with a data type.
ColumnExists Checks if columns exist in a dataset. This allows customers building self-service data platforms to ensure certain columns are made available.
ColumnLength Checks if length of data is consistent.
ColumnNamesMatchPattern Checks if column names match defined patterns. Useful for governance teams to enforce column name consistency.
ColumnValues Checks if data is consistent per defined values. This rule supports regular expressions.
Completeness Checks for any blank or NULLs in data.
CustomSql Customers can implement almost any type of data quality checks in SQL.
DataFreshness Checks if data is fresh.
DatasetMatch Compares two datasets and identifies if they are in sync.
DistinctValuesCount Checks for duplicate values.
Entropy Checks for entropy of the data.
IsComplete Checks if 100% of the data is complete.
IsPrimaryKey Checks if a column is a primary key (not NULL and unique).
IsUnique Checks if 100% of the data is unique.
Mean Checks if the mean matches the set threshold.
ReferentialIntegrity Checks if two datasets have referential integrity.
RowCount Checks if record counts match a threshold.
RowCountMatch Checks if record counts between two datasets match.
StandardDeviation Checks if standard deviation matches the threshold.
SchemaMatch Checks if schema between two datasets match.
Sum Checks if sum matches a set threshold.
Uniqueness Checks if uniqueness of dataset matches a threshold.
UniqueValueRatio Checks if the unique value ration matches a threshold.
  • Embedded in customer workflow – AWS Glue Data Quality has to blend into customer workflows for it to be useful. Disjointed experiences create friction in getting started. You can access AWS Glue Data Quality from the AWS Glue Data Catalog, allowing data stewards to set up rules while they are using the Data Catalog. You can also access AWS Glue Data Quality from Glue Studio (AWS Glue’s visual authoring tool), Glue Studio notebooks (a notebook-based interface for coders to create data integration pipelines), and interactive sessions, an API where data engineers can submit jobs from their choice of code editor.
  • Pay-as-you-go and cost-effective – AWS Glue Data Quality is charged based on the compute used. This simple pricing model doesn’t lock you into annual licenses. AWS Glue ETL-based data quality checks can use Flex execution, which is 34% cheaper for non-SLA sensitive data quality checks. Additionally, AWS Glue Data Quality rules on data pipelines can help you save costs because you don’t have to waste compute resources on bad quality data when detected early. Also, when data quality checks are configured as part of data pipelines, you only incur an incremental cost because the data is already read and mostly in memory.
  • Built on open-source – AWS Glue Data Quality is built on open-source DeeQu, a library that is used internally by Amazon to manage the quality of data lakes over 60 PB. DeeQu is optimized to run data quality rules in minimal passes that makes it efficient. The rules that are authored in AWS Glue Data Quality can be run in any environment that can run DeeQu, allowing you to stay in an open-source solution.
  • Simplified rule authoring language – As part of AWS Glue Data Quality, we announced Data Quality Definition Language (DQDL). DQDL attempts to standardize data quality rules so that you can use the same data quality rules across different databases and engines. DQDL is simple to author and read, and brings the goodness of code that developers like, such as version control and deployment. To demonstrate the simplicity of this language, the following example shows three rules that check if record counts are greater than 10, and ensures that VendorID doesn’t have any empty values and VendorID has a certain range of values:
    Rules = [
        RowCount > 10,
        IsComplete "VendorID",
        ColumnValues "VendorID" in ["1", "2", "3", "4"]
        ]

General Availability features

AWS Glue Data Quality has several key enhancements from the preview version:

  • Error record identification – You need to know which records failed data quality checks. We have launched this capability in AWS Glue ETL, where the data quality transform now enriches the input dataset with new columns that identify which records failed data quality checks. This can help you quarantine bad data so that only good records flow into your data repositories.
  • New rule types that validate data across multiple datasets – With new rule types like ReferentialIntegrity, DatasetMatches, RowCountMatches, and AggregateMatches, you can compare two datasets to ensure that data integrity is maintained. The SchemaMatch rule type ensures that the dataset accurately matches a set schema, preventing downstream errors that may be caused by schema changes.
  • Amazon EventBridge integration – Integration with Amazon EventBridge enables you to simplify how you set up alerts when quality rules fail. A one-time setup is now sufficient to alert data consumers about data quality failures.
  • AWS CloudFormation support – With support for AWS CloudFormation, AWS Glue Data Quality now enables you to easily deploy data quality rules in many environments
  • Join support in CustomSQL rule type – You can now join datasets in CustomSQL rule types to write complex business rules.
  • New data source support – You can check data quality on open transactional formats such as Apache HUDI, Apache Iceberg, and Delta Lake. Additionally, you can set up data quality rules on Amazon Redshift and Amazon Relational Database Service (Amazon RDS) data sources cataloged in the AWS Glue Data Catalog.

Summary

AWS Data Quality is now Generally Available. To help you get started, we have created a five-part blog series:

Get started today with AWS Glue Data Quality and tell us what you think.


About the authors

Shiv Narayanan is a Technical Product Manager for AWS Glue’s data management capabilities like data quality, sensitive data detection and streaming capabilities. Shiv has over 20 years of data management experience in consulting, business development and product management.

Tome Tanasovski is a Technical Manager at AWS, for a team that manages capabilities into Amazon’s big data platforms via AWS Glue. Prior to working at AWS, Tome was an executive for a market-leading global financial services firm in New York City where he helped run the Firm’s Artificial Intelligence & Machine Learning Center of Excellence. Prior to this role he spent nine years in the Firm focusing on automation, cloud, and distributed computing. Tome has a quarter-of-a-century worth of experience in technology in the Tri-state area across a wide variety of industries including big tech, finance, insurance, and media.

Brian Ross is a Senior Software Development Manager at AWS.  He has spent 24 years building software at scale and currently focuses on serverless data integration with AWS Glue. In his spare time, he studies ancient texts, cooks modern dishes and tries to get his kids to do both.

Alona Nadler is AWS Glue Head of Product and is responsible for AWS Glue Service. She has a long history of working in the enterprise software and data services spaces. When not working, Alona enjoys traveling and playing tennis.

AWS Week in Review – Amazon Security Lake Now GA, New Actions on AWS Fault Injection Simulator, and More – June 5, 2023

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-week-in-review-amazon-security-lake-now-ga-new-actions-on-aws-fault-injection-simulator-and-more-june-5-2023/

Last Wednesday, I traveled to Cape Town to speak at the .Net Developer User Group. My colleague Francois Bouteruche also gave a talk but joined virtually. I enjoyed my time there—what an amazing community! Join the group in order to learn about upcoming events.

Now onto the AWS updates from last week. There was a lot of news related to AWS, and I have compiled a few announcements you need to know. Let’s get started!

Last Week’s Launches
Here are a few launches from last week that you might have missed:

Amazon Security Lake is now Generally Available – This service automatically centralizes security data from AWS environments, SaaS providers, on-premises environments, and cloud sources into a purpose-built data lake stored in your account, making it easier to analyze security data, gain a more comprehensive understanding of security across your entire organization, and improve the protection of your workloads, applications, and data. Read more in Channy’s post announcing the preview of Security Lake.

New AWS Direct Connect Location in Santiago, Chile – The AWS Direct Connect service lets you create a dedicated network connection to AWS. With this service, you can build hybrid networks by linking your AWS and on-premises networks to build applications that span environments without compromising performance. Last week we announced the opening of a new AWS Direct Connect location in Santiago, Chile. This new Santiago location offers dedicated 1 Gbps and 10 Gbps connections, with MACsec encryption available for 10 Gbps. For more information on over 115 Direct Connect locations worldwide, visit the locations section of the Direct Connect product detail pages.

New actions on AWS Fault Injection Simulator for Amazon EKS and Amazon ECS – Had it not been for Adrian Hornsby’s LinkedIn post I would have missed this announcement. We announced the expanded support of AWS Fault Injection Simulator (FIS) for Amazon Elastic Kubernetes Service (EKS) and Amazon Elastic Container Service (ECS). This expanded support adds additional AWS FIS actions for Amazon EKS and Amazon ECS. Learn more about Amazon ECS task actions here, and Amazon EKS pod actions here.

Other AWS News
A few more news items and blog posts you might have missed:

Autodesk Uses Sagemaker to Improve Observability – One of our customers, Autodesk, used AWS services including Amazon Sagemaker, Amazon Kinesis, and Amazon API Gateway to build a platform that enables development and deployment of near-real time personalization experiments by modeling and responding to user behavior data. All this delivered a dynamic, personalized experience for Autodesk’s customers. Read more about the story at AWS Customer Stories.

AWS DMS Serverless – We announced AWS DMS Serverless which lets you automatically provision and scale capacity for migration and data replication. Donnie wrote about this announcement here.

For AWS open-source news and updates, check out the latest newsletter curated by my colleague Ricardo Sueiras to bring you the most recent updates on open-source projects, posts, events, and more.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Upcoming AWS Events
We have the following upcoming events. These give you the opportunity to meet with other tech enthusiasts and learn:

AWS Silicon Innovation Day (June 21) – A one-day virtual event that will allow you to understand AWS Silicon and how you can use AWS’s unique silicon offerings to innovate. Learn more and register here.

AWS Global Summits – Sign up for the AWS Summit closest to where you live: London (June 7), Washington, DC (June 7–8), Toronto (June 14).

AWS Community Days – Join these community-led conferences where event logistics and content are planned, sourced, and delivered by community leaders: Chicago, Illinois (June 15), and Chile (July 1).

And with that, I end my very first Week in Review post, and this was such fun to write. Come back next Monday for another Week in Review!

– Veliswa x

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

New eBook: 5 Keys to Secure Enterprise Messaging

Post Syndicated from Anne Grahn original https://aws.amazon.com/blogs/security/new-ebook-5-keys-to-secure-enterprise-messaging/

AWS is excited to announce a new eBook, 5 Keys to Secure Enterprise Messaging. The new eBook includes best practices for addressing the security and compliance risks associated with messaging apps.

An estimated 3.09 billion mobile phone users access messaging apps to communicate, and this figure is projected to grow to 3.51 billion users in 2025.

Legal and regulatory requirements for data protection, privacy, and data retention have made protecting business communications a priority for organizations across the globe. Although consumer messaging apps are convenient and support real-time communication with colleagues, customers, and partners, they often lack the robust security and administrative controls many businesses require.

The eBook details five keys to secure enterprise messaging that balance people, process, and technology.

We encourage you to read the eBook, and learn about:

  • Establishing messaging policies and guidelines that are effective for your workforce
  • Training employees to use messaging apps in a way that doesn’t increase organizational risk
  • Building a security-first culture
  • Using true end-to-end encryption (E2EE) to secure communications
  • Retaining data to help meet requirements, without exposing it to outside parties

Download 5 Keys to Secure Enterprise Messaging.

 
If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security news? Follow us on Twitter.

Anne Grahn

Anne Grahn

Anne is a Senior Worldwide Security GTM Specialist at AWS based in Chicago. She has more than a decade of experience in the security industry, and focuses on effectively communicating cybersecurity risk. She maintains a Certified Information Systems Security Professional (CISSP) certification.

New – AWS DMS Serverless: Automatically Provisions and Scales Capacity for Migration and Data Replication

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/new-aws-dms-serverless-automatically-provisions-and-scales-capacity-for-migration-and-data-replication/

With the vast amount of data being created today, organizations are moving to the cloud to take advantage of the security, reliability, and performance of fully managed database services. To facilitate database and analytics migrations, you can use AWS Database Migration Service (AWS DMS). First launched in 2016, AWS DMS offers a simple migration process that automates database migration projects, saving time, resources, and money.

Although you can start AWS DMS migration with a few clicks through the console, you still need to do research and planning to determine the required capacity before migrating. It can be challenging to know how to properly scale capacity ahead of time, especially when simultaneously migrating many workloads or continuously replicating data. On top of that, you also need to continually monitor usage and manually scale capacity to ensure optimal performance.

Introducing AWS DMS Serverless
Today, I’m excited to tell you about AWS DMS Serverless, a new serverless option in AWS DMS that automatically sets up, scales, and manages migration resources to make your database migrations easier and more cost-effective.

Here’s a quick preview on how AWS DMS Serverless works:

AWS DMS Serverless removes the guesswork of figuring out required compute resources and handling the operational burden needed to ensure a high-performance, uninterrupted migration. It performs automatic capacity provisioning, scaling, and capacity optimization of migrations, allowing you to quickly begin migrations with minimal oversight.

At launch, AWS DMS Serverless supports Microsoft SQL Server, PostgreSQL, MySQL, and Oracle as data sources. As for data targets, AWS DMS Serverless supports a wide range of databases and analytics services, from Amazon Aurora, Amazon Relational Database Service (Amazon RDS), Amazon Simple Storage Service (Amazon S3), Amazon Redshift, Amazon DynamoDB, and more. AWS DMS Serverless continues to add support for new data sources and targets. Visit Supported Engine Versions to stay updated.

With a variety of sources and targets supported by AWS DMS Serverless, many scenarios become possible. You can use AWS DMS Serverless to migrate databases and help to build modern data strategies by synchronizing ongoing data replications into data lakes (e.g., Amazon S3) or data warehouses (e.g., Amazon Redshift) from multiple, perhaps disparate data sources.

How AWS DMS Serverless Works
Let me show you how you can get started with AWS DMS Serverless. In this post, I migrate my data from a source database running on PostgreSQL to a target MySQL database running on Amazon RDS. The following screenshot shows my source database with dummy data:

As for the target, I’ve set up a MySQL database running in Amazon RDS. The following screenshot shows my target database:

Getting starting with AWS DMS Serverless is similar to how AWS DMS works today. AWS DMS Serverless requires me to complete the setup tasks such as creating a virtual private cloud (VPC) to defining source and target endpoints. If this is your first time working with AWS DMS, you can learn more by visiting Prerequisites for AWS Database Migration Service.

To connect to a data store, AWS DMS needs endpoints for both source and target data stores. An endpoint provides all necessary information including connection, data store type, and location to my data stores. The following image shows an endpoint I’ve created for my target database:

When I have finished setting up the endpoints, I can begin to create a replication by selecting the Create replication button on the Serverless replications page. Replication is a new concept introduced in AWS DMS Serverless to abstract instances and tasks that we normally have in standard AWS DMS. Additionally, the capacity resources are managed independently for each replication.

On the Create replication page, I need to define some configurations. This starts with defining Name, then specifying Source database endpoint and Target database endpoint. If you don’t find your endpoints, make sure you’re selecting database engines supported by AWS DMS Serverless.

After that, I need to specify the Replication type. There are three types of replication available in AWS DMS Serverless:

  • Full load — If I need to migrate all existing data in source database
  • Change data capture (CDC) — If I have to replicate data changes from source to target database.
  • Full load and change data capture (CDC) — If I need to migrate existing data and replicate data changes from source to target database.

In this example, I chose Full load and change data capture (CDC) because I need to migrate existing data and continuously update the target database for ongoing changes on the source database.

In the Settings section, I can also enable logging with Amazon CloudWatch, which makes it easier for me to monitor replication progress over time.

As with standard AWS DMS, in AWS DMS Serverless, I can also configure Selection rules in Table mappings to define filters that I need to replicate from table columns in the source data store.

I can also use Transformation rules if I need to rename a schema or table or add a prefix or suffix to a schema or table.

In the Capacity section, I can set the range for required capacity to perform replication by defining the minimum and maximum DCU (DMS capacity units). The minimum DCU setting is optional because AWS DMS Serverless determines the minimum DCU based on an assessment of the replication workload. During replication process, AWS DMS uses this range to scale up and down based on CPU utilization, connections, and available memory.

Setting the maximum capacity allows you to manage costs by making sure that AWS DMS Serverless never consumes more resources than you have budgeted for. When you define the maximum DCU, make sure that you choose a reasonable capacity so that AWS DMS Serverless can handle large bursts of data transaction volumes. If traffic volume decreases, AWS DMS Serverless scales capacity down again, and you only pay for what you need. For cases in which you want to change the minimum and maximum DCU settings, you have to stop the replication process first, make the changes, and run the replication again.

When I’m finished with configuring replication, I select Create replication.

When my replication is created, I can view more details of my replication and start the process by selecting Start.

After my replication runs for around 40 minutes, I can monitor replication progress in the Monitoring tab. AWS DMS Serverless also has a CloudWatch metric called Capacity utilization, which indicates the use of capacity to run replication according to the range defined as minimum and maximum DCU. The following screenshot shows the capacity scales up in the CloudWatch metrics chart.

When the replication finishes its process, I see the capacity starting to decrease. This indicates that in addition to AWS DMS Serverless successfully scaling up to the required capacity, it can also scale down within the range I have defined.

Finally, all I need to do is verify whether my data has been successfully replicated into the target data store. I need to connect to the target, run a select query, and check if all data has been successfully replicated from the source.

Now Available
AWS DMS Serverless is now available in all commercial regions where standard AWS DMS is available, and you can start using it today. For more information about benefits, use cases, how to get started, and pricing details, refer to AWS DMS Serverless.

Happy migrating!
—Donnie

Announcing the AWS Blueprint for Ransomware Defense

Post Syndicated from Jeremy Ware original https://aws.amazon.com/blogs/security/announcing-the-aws-blueprint-for-ransomware-defense/

In this post, Amazon Web Services (AWS) introduces the AWS Blueprint for Ransomware Defense, a new resource that both enterprise and public sector organizations can use to implement preventative measures to protect data from ransomware events. The AWS Blueprint for Ransomware Defense provides a mapping of AWS services and features as they align to aspects of the Center for Internet Security (CIS) Critical Security Controls (CIS Controls). This information can be used to help customers assess and protect their data from ransomware events.

The following is background on ransomware, CIS, and the initiatives that led to the publication of this new blueprint.

The Ransomware Task Force

In April of 2021, the U.S. government launched the Ransomware Task Force (RTF), which has the mission of uniting key stakeholders across industry, government, and civil society to create new solutions, break down silos, and find effective new methods of countering the ransomware threat. The RTF has since launched several progress reports with specific recommendations, including the development of the RTF Blueprint for Ransomware Defense, which provides a framework with practical steps to mitigate, respond to, and recover from ransomware. AWS is a member of the RTF, and we have taken action to create our own AWS Blueprint for Ransomware Defense that maps actionable and foundational security controls to AWS services and features that customers can use to implement those controls. The AWS Blueprint for Ransomware Defense is based on the CIS Controls framework.

Center for Internet Security

The Center for Internet Security (CIS) is a community-driven nonprofit, globally recognized for establishing best practices for securing IT systems and data. To help establish foundational defense mechanisms, a subset of the CIS Critical Security Controls (CIS Controls) have been identified as important first steps in the implementation of a robust program to prevent, respond to, and recover from ransomware events. This list of controls was established to provide safeguards against the most impactful and well-known internet security issues. The controls have been further prioritized into three implementation groups (IGs), to help guide their implementation. IG1, considered “essential cyber hygiene,” provides foundational safeguards. IG2 builds on IG1 by including the controls in IG1 plus a number of additional considerations. Finally, IG3 includes the controls in IG1 and IG2, with an additional layer of controls that protect against more sophisticated security issues.

CIS recommends that organizations use the CIS IG1 controls as basic preventative steps against ransomware events. We’ve produced a mapping of AWS services that can help you implement aspects of these controls in your AWS environment. Ransomware is a complex event, and the best course of action to mitigate risk is to apply a thoughtful strategy of defense in depth. The mitigations and controls outlined in this mapping document are general security best practices, but are a non-exhaustive list.

Because data is often vital to the operation of mission-critical services, ransomware can severely disrupt business processes and applications that depend on this data. For this reason, many organizations are looking for effective security controls that will improve their security posture against these types of events. We hope you find the information in the AWS Blueprint for Ransomware Defense helpful and incorporate it as a tool to provide additional layers of security to help keep your data safe.

Let us know if you have any feedback through the AWS Security Contact Us page. Please reach out if there is anything we can do to add to the usefulness of the blueprint or if you have any additional questions on security and compliance. You can find more information from the IST (Institute for Security and Technology) describing ransomware and how to protect yourself on the IST website.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Jeremy Wave

Jeremy Ware

Jeremy is a Security Specialist Solutions Architect focused on Identity and Access Management. Jeremy and his team enable AWS customers to implement sophisticated, scalable, and secure IAM architecture and Authentication workflows to solve business challenges. With a background in Security Engineering, Jeremy has spent many years working to raise the Security Maturity gap at numerous global enterprises. Outside of work, Jeremy loves to explore the mountainous outdoors, and participate in sports such as snowboarding, wakeboarding, and dirt bike riding.

Author

Megan O’Neil

Megan is a Principal Security Specialist Solutions Architect focused on Threat Detection and Incident Response. Megan and her team enable AWS customers to implement sophisticated, scalable, and secure solutions that solve their business challenges. Outside of work, Megan loves to explore Colorado, including mountain biking, skiing, and hiking.

Luis Pastor

Luis Pastor

Luis is a Senior Security Solutions Architect focused on infrastructure security at AWS. Before AWS, he worked with both large and boutique system integrators, helping clients in an array of industries to improve their security posture and reach and maintain compliance in hybrid environments. Luis enjoys keeping active, cooking, and eating spicy food—especially Mexican cuisine.

Updated whitepaper available: Architecting for PCI DSS Segmentation and Scoping on AWS

Post Syndicated from Ted Tanner original https://aws.amazon.com/blogs/security/updated-whitepaper-available-architecting-for-pci-dss-segmentation-and-scoping-on-aws/

Amazon Web Services (AWS) has re-published the whitepaper Architecting for PCI DSS Scoping and Segmentation on AWS to provide guidance on how to properly define the scope of your Payment Card Industry (PCI) Data Security Standard (DSS) workloads that are running in the AWS Cloud. The whitepaper has been refreshed to include updated AWS best practices and technologies, and updates that are applicable to the new PCI DSS v4.0 requirements. The whitepaper looks at how to define segmentation boundaries between your in-scope and out-of-scope resources by using cloud-based AWS services.

The whitepaper is intended for engineers and solution builders, but it also serves as a guide for Qualified Security Assessors (QSAs) and internal security assessors (ISAs) to better understand the different segmentation controls that are available within AWS products and services, along with associated scoping considerations.

Compared to on-premises environments, software-defined networking on AWS transforms the scoping process for applications by providing additional segmentation controls beyond network segmentation. Thoughtful design of your applications and selection of security-impacting services for implementing your required controls can reduce the number of systems and services in your cardholder data environment (CDE).

The whitepaper is based on the PCI Council’s Information Supplement: Guidance for PCI DSS Scoping and Network Segmentation.

 
If you have questions or want to learn more, contact your account representative, or leave a comment below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Ted Tanner

Ted Tanner

Ted is a Principal Assurance Consultant and PCI DSS Qualified Security Assessor with AWS Security Assurance Services, and has more than 25 years of IT and security experience. He uses this experience to provide AWS customers with guidance on compliance and security, and on building and optimizing their cloud compliance programs. He is co-author of the Payment Card Industry Data Security Standard (PCI DSS) v3.2.1 on AWS Compliance Guide and the soon-to-be-released v4.0 edition.

Author

Avik Mukherjee

Avik is a Senior Security Consultant with more than 15 years of experience in IT governance, security, risk, and compliance. He has background of being a QSA for PCI DSS and point-to-point encryption (P2PE) and has deep knowledge of security advisory and assessment work in various industries, including retail, financial, and technology.

Joseph Okonkwo

Joseph Okonkwo

Joseph is a Senior Security Architect and PCI DSS Professional (PCIP), and has more than a decade of experience in application security, security architecture, and as an Internal Security Assessor (ISA). He works closely with AWS clients to enable digital transformation and migration in the Professional Services team. Joseph earned an MBA from Imperial College, Business School, and a M.S. in Data Telecommunications & Networks from The University of Salford in Manchester.
New – Snowball Edge Storage Optimized Devices with More Storage and Bandwidth

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-snowball-edge-storage-optimized-devices-with-more-storage-and-bandwidth/

AWS Snow Family family devices are used to cost-effectively move data to the cloud and to process data at the edge. The enhanced Snowball Edge Storage Optimized devices are designed for your petabyte-scale data migration projects, with 210 terabytes of NVMe storage and the ability to transfer up to 1.5 gigabytes of data per second. The devices also include several connectivity options: 10GBASE-T, SFP48, and QSFP28.

Large Data Migration
In order to make your migration as smooth and efficient as possible, we now have a well-defined Large Data Migration program. As part of this program, we will work with you to make sure that your site is able to support rapid data transfer, and to set up a proof-of-concept migration. If necessary, we will also recommend services and solutions from our AWS Migration Competency Partners. After successful completion of the proof-of-concept you will be familiar with the Snow migration process, and you will be ready to order devices using the process outlined below.

You can make use of the Large Data Migration program by contacting AWS Sales Support.

Ordering Devices
While you can order and manage devices individually, you can save time and reduce complexity by using a large data migration plan. Let’s walk through the process of creating one. I open the AWS Snow Family Console and click Create your large data migration plan:

I enter a name for my migration plan (MediaMigrationPlan), and select or enter the shipping address of my data center:

Then I specify the amount of data that I plan to migrate, and the number of devices that I want to use concurrently (taking into account space, power, bandwidth, and logistics within my data center):

When everything looks good I click Create data migration plan to proceed and my plan becomes active:

I can review the Monitoring section my my plan to see how my migration is going (these are simply Amazon CloudWatch metrics and I can add them to a dashboard, set alarms, and so forth):

The Jobs section includes a recommended job ordering schedule that takes the maximum number of concurrent devices into account:

When I am ready to start transferring data, I visit the Jobs ordered tab and create a Snow job:

As the devices arrive, I connect them to my network and copy data to them via S3 (read Managing AWS Storage) or NFS (read Using NFS File Shares to Manage File Storage), then return it to AWS for ingestion!

Things to Know
Here are a couple of fun facts about this enhanced device:

Regions – Snowball Edge Storage Optimized Devices with 210 TB of storage are available in the US East (N. Virginia) and US West (Oregon) AWS Regions.

Pricing – You pay for the use of the device and for data transfer in and out of AWS, with on-demand and committed upfront pricing available. To learn more about pricing for Snowball Edge Storage Optimized 210 TB devices contact your AWS account team or AWS Sales Support.

— Jeff;