Today we are thrilled to announce the general availability of Amazon Security Lake, first announced in a preview release at 2022 re:Invent. Security Lake centralizes security data from Amazon Web Services (AWS) environments, software as a service (SaaS) providers, on-premises, and cloud sources into a purpose-built data lake that is stored in your AWS account. With Open Cybersecurity Schema Framework (OCSF) support, the service normalizes and combines security data from AWS and a broad range of security data sources. This helps provide your team of analysts and security engineers with broad visibility to investigate and respond to security events, which can facilitate timely responses and helps to improve your security across multicloud and hybrid environments.
Figure 1 shows how Security Lake works, step by step. In this post, we discuss these steps, highlight some of the most popular use cases for Security Lake, and share the latest enhancements and updates that we have made since the preview launch.
Figure 1: How Security Lake works
Target use cases
In this section, we showcase some of the use cases that customers have found to be most valuable while the service was in preview.
Facilitate your security investigations with elevated visibility
Amazon Security Lake helps to streamline security investigations by aggregating, normalizing, and optimizing data storage in a single security data lake. Security Lake automatically normalizes AWS logs and security findings to the OCSF schema. This includes AWS CloudTrail management events, Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, Amazon Route 53 Resolver query logs, and AWS Security Hub security findings from Amazon security services, including Amazon GuardDuty, Amazon Inspector, and AWS IAM Access Analyzer, as well as security findings from over 50 partner solutions. By having security-related logs and findings in a centralized location, and in the same format, Security Operations teams can streamline their process and devote more time to investigating security issues. This centralization reduces the need to spend valuable time collecting and normalizing logs into a specific format.
Figure 2 shows the Security Lake activation page, which presents users with options to enable log sources, AWS Regions, and accounts.
Figure 2: Security Lake activation page with options to enable log sources, Regions, and accounts
Figure 3 shows another section of the Security Lake activation page, which presents users with options to set rollup Regions and storage classes.
Figure 3: Security Lake activation page with options to select a rollup Region and set storage classes
Simplify your compliance monitoring and reporting
With Security Lake, customers can centralize security data into one or more rollup Regions, which can help teams to simplify their regional compliance and reporting obligations. Teams often face challenges when monitoring for compliance across multiple log sources, Regions, and accounts. By using Security Lake to collect and centralize this evidence, security teams can significantly reduce the time spent on log discovery and allocate more time towards compliance monitoring and reporting.
Analyze multiple years of security data quickly
Security Lake offers integration with third-party security services such as security information and event management (SIEM) and extended detection and response (XDR) tools, as well as popular data analytics services like Amazon Athena and Amazon OpenSearch Service to quickly analyze petabytes of data. This enables security teams to gain deep insights into their security data and take nimble measures to help protect their organization. Security Lake helps enforce least-privilege controls for teams across organizations by centralizing data and implementing robust access controls, automatically applying policies that are scoped to the required subscribers and sources. Data custodians can use the built-in features to create and enforce granular access controls, such as to restrict access to the data in the security lake to only those who require it.
Figure 4 depicts the process of creating a data access subscriber within Security Lake.
Figure 4: Creating a data access subscriber in Security Lake
Unify security data management across hybrid environments
The centralized data repository in Security Lake provides a comprehensive view of security data across hybrid and multicloud environments, helping security teams to better understand and respond to threats. You can use Security Lake to store security-related logs and data from various sources, including cloud-based and on-premises systems, making it simpler to collect and analyze security data. Additionally, by using automation and machine learning solutions, security teams can help identify anomalies and potential security risks more efficiently. This can ultimately lead to better risk management and enhance the overall security posture for the organization. Figure 5 illustrates the process of querying AWS CloudTrail and Microsoft Azure audit logs simultaneously by using Amazon Athena.
Figure 5: Querying AWS CloudTrail and Microsoft Azure audit logs together in Amazon Athena
Updates since preview launch
Security Lake automatically normalizes logs and events from natively supported AWS services to the OCSF schema. With the general availability release, Security Lake now supports the latest version of OCSF, which is version 1 rc2. CloudTrail management events are now normalized into three distinct OCSF event classes: Authentication, Account Change, and API Activity.
We made various improvements to resource names and schema mapping to enhance the usability of logs. Onboarding is made simpler with automated AWS Identity and Access Management (IAM) role creation from the console. Additionally, you have the flexibility to collect CloudTrail sources independently including management events, Amazon Simple Storage Service (Amazon S3) data events, and AWS Lambda events.
To enhance query performance, we made a transition from hourly to daily time partitioning in Amazon S3, resulting in faster and more efficient data retrieval. Also, we added Amazon CloudWatch metrics to enable proactive monitoring of your log ingestion process to facilitate the identification of collection gaps or surges.
New Security Lake account holders are eligible for a 15-day free trial in supported Regions. Security Lake is now generally available in the following AWS Regions: US East (Ohio), US East (N. Virginia), US West (Oregon), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo), Europe (Frankfurt), Europe (Ireland), Europe (London), and South America (São Paolo).
The AWS Professional Services organization is a global team of experts that can help customers realize their desired business outcomes when using AWS. Our teams of data architects and security engineers engage with customer Security, IT, and business leaders to develop enterprise solutions. We follow current recommendations to support customers in their journey to integrate data into Security Lake. We integrate ready-built data transformations, visualizations, and AI/machine learning (ML) workflows that help Security Operations teams rapidly realize value. If you are interested in learning more, reach out to your AWS Professional Services account representative.
Summary
We invite you to explore the benefits of using Amazon Security Lake by taking advantage of our 15-day free trial and providing your feedback on your experiences, use cases, and solutions. We have several resources to help you get started and build your first data lake, including comprehensive documentation, demo videos, and webinars. By giving Security Lake a try, you can experience firsthand how it helps you centralize, normalize, and optimize your security data, and ultimately streamline your organization’s security incident detection and response across multicloud and hybrid environments.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
We are excited to announce that the AWS SDK for Java 2.x now offers the Enhanced Document API for DynamoDB, providing an enhanced way of working with Amazon DynamoDb items. This post covers using the Enhanced Document API for DynamoDB with the DynamoDB Enhanced Client. By using the Enhanced Document API, you can create an EnhancedDocument instance to represent an item with no fixed schema, and then use the DynamoDB Enhanced Client to read and write to DynamoDB. Furthermore, unlike the Document APIs of aws-sdk-java 1.x, which provided arguments and return types that were not type-safe, the EnhancedDocument provides strongly-typed APIs for working with documents. This interface simplifies the development process and ensures that the data is correctly typed.
Prerequisites:
Before getting started, ensure you are using an up-to-date version of the AWS Java SDK dependency with all the latest released bug-fixes and features. For Enhanced Document API support, you must use version 2.20.33 or later. See our “Set up an Apache Maven project” guide for details on how to manage the AWS Java SDK dependency in your project.
Quick walk-through for using Enhanced Document API to interact with DDB
Step 1 : Create a DynamoDB Enhanced Client
Create an instance of the DynamoDbEnhancedClient class, which provides a high-level interface for Amazon DynamoDB that simplifies working with DynamoDB tables.
Step 2 : Create a DynamoDbTable resource object with Document table schema
To execute commands against a DynamoDB table using the Enhanced Document API, you must associate the table with your Document table schema to create a DynamoDbTable resource object. The Document table schema builder requires the primary index key and attribute converter providers. Use AttributeConverterProvider.defaultProvider() to convert document attributes of default types. An optional secondary index key can be added to the builder.
DynamoDbTable<EnhancedDocument> documentTable = enhancedClient.table("my_table",
                                              TableSchema.documentSchemaBuilder()
                                                         .addIndexPartitionKey(TableMetadata.primaryIndexName(),"hashKey", AttributeValueType.S)
                                                         .addIndexSortKey(TableMetadata.primaryIndexName(), "sortKey", AttributeValueType.N)
                                                         .attributeConverterProviders(AttributeConverterProvider.defaultProvider())
                                                         .build());

// call documentTable.createTable() if "my_table" does not exist in DynamoDB
Step 3 : Write a DynamoDB item using an EnhancedDocument
The EnhancedDocument class has static factory methods along with a builder method to add attributes to a document. The following snippet demonstrates the type safety provided by EnhancedDocument when you construct a document item.
AttributeConverterProviders for accessing document attributes as custom objects
You can provide a custom AttributeConverterProvider instance to an EnhancedDocument to convert document attributes to a specific object type. These providers can be set on either DocumentTableSchema or EnhancedDocument to read or write attributes as custom objects.
TableSchema.documentSchemaBuilder()
           .attributeConverterProviders(CustomClassConverterProvider.create(), defaultProvider())
           .build();

// Insert a custom class instance into an EnhancedDocument as attribute 'customMapOfAttribute'.
EnhancedDocument customAttributeDocument =
EnhancedDocument.builder().put("customMapOfAttribute", customClassInstance, CustomClass.class).build();

// Retrieve attribute 'customMapOfAttribute' as CustomClass object.
CustomClass customClassObject = customAttributeDocument.get("customMapOfAttribute", CustomClass.class);
Convert Documents to JSON and vice-versa
The Enhanced Document API allows you to convert a JSON string to an EnhancedDocument and vice-versa.
// Enhanced document created from JSON string using defaultConverterProviders.
EnhancedDocument documentFromJson = EnhancedDocument.fromJson("{\"key\": \"Value\"}")

// Converting an EnhancedDocument to JSON string "{\"key\": \"Value\"}"
String jsonFromDocument = documentFromJson.toJson();
Define a Custom Attribute Converter Provider
Custom attribute converter providers are implementations of AttributeConverterProvider that provide converters for custom classes. Below is an example for a CustomClassForDocumentAPI which has as a single field stringAttribute of type String and its corresponding AttributeConverterProvider implementation.
public class CustomClassForDocumentAPI {
    private final String stringAttribute;

    public CustomClassForDocumentAPI(Builder builder) {
        this.stringAttribute = builder.stringAttribute;
    }
    public static Builder builder() {
        return new Builder();
    }
    public String stringAttribute() {
        return stringAttribute;
    }
    public static final class Builder {
        private String stringAttribute;
        private Builder() {
        }
        public Builder stringAttribute(String stringAttribute) {
            this.stringAttribute = string;
            return this;
        }
        public CustomClassForDocumentAPI build() {
            return new CustomClassForDocumentAPI(this);
        }
    }
}
import java.util.Map;
import software.amazon.awssdk.enhanced.dynamodb.AttributeConverter;
import software.amazon.awssdk.enhanced.dynamodb.AttributeConverterProvider;
import software.amazon.awssdk.enhanced.dynamodb.EnhancedType;
import software.amazon.awssdk.utils.ImmutableMap;

public class CustomAttributeForDocumentConverterProvider implements AttributeConverterProvider {
    private final Map<EnhancedType<?>, AttributeConverter<?>> converterCache = ImmutableMap.of(
        EnhancedType.of(CustomClassForDocumentAPI.class), new CustomClassForDocumentAttributeConverter());
        // Different types of converters can be added to this map.

    public static CustomAttributeForDocumentConverterProvider create() {
        return new CustomAttributeForDocumentConverterProvider();
    }

    @Override
    public <T> AttributeConverter<T> converterFor(EnhancedType<T> enhancedType) {
        return (AttributeConverter<T>) converterCache.get(enhancedType);
    }
}
A custom attribute converter is an implementation of AttributeConverter that converts a custom classes to and from a map of attribute values, as shown below.
import java.util.LinkedHashMap;
import java.util.Map;
import software.amazon.awssdk.enhanced.dynamodb.AttributeConverter;
import software.amazon.awssdk.enhanced.dynamodb.AttributeValueType;
import software.amazon.awssdk.enhanced.dynamodb.EnhancedType;
import software.amazon.awssdk.enhanced.dynamodb.internal.converter.attribute.EnhancedAttributeValue;
import software.amazon.awssdk.enhanced.dynamodb.internal.converter.attribute.StringAttributeConverter;
import software.amazon.awssdk.services.dynamodb.model.AttributeValue;

public class CustomClassForDocumentAttributeConverter implements AttributeConverter<CustomClassForDocumentAPI> {
    public static CustomClassForDocumentAttributeConverter create() {
        return new CustomClassForDocumentAttributeConverter();
    }
    @Override
    public AttributeValue transformFrom(CustomClassForDocumentAPI input) {
        Map<String, AttributeValue> attributeValueMap = new LinkedHashMap<>();
        if(input.string() != null){
            attributeValueMap.put("stringAttribute", AttributeValue.fromS(input.string()));
        }
        return EnhancedAttributeValue.fromMap(attributeValueMap).toAttributeValue();
    }

    @Override
    public CustomClassForDocumentAPI transformTo(AttributeValue input) {
        Map<String, AttributeValue> customAttr = input.m();
        CustomClassForDocumentAPI.Builder builder = CustomClassForDocumentAPI.builder();
        if (customAttr.get("stringAttribute") != null) {
            builder.stringAttribute(StringAttributeConverter.create().transformTo(customAttr.get("stringAttribute")));
        }
        return builder.build();
    }
    @Override
    public EnhancedType<CustomClassForDocumentAPI> type() {
        return EnhancedType.of(CustomClassForDocumentAPI.class);
    }
    @Override
    public AttributeValueType attributeValueType() {
        return AttributeValueType.M;
    }
}
Attribute Converter Provider for EnhancedDocument Builder
When working outside of a DynamoDB table context, make sure to set the attribute converter providers explicitly on the EnhancedDocument builder. When used within a DynamoDB table context, the table schema’s converter provider will be used automatically for the EnhancedDocument. The code snippet below shows how to set an AttributeConverterProvider using the EnhancedDocument builder method.
// Enhanced document created from JSON string using custom AttributeConverterProvider.
EnhancedDocument documentFromJson = EnhancedDocument.builder()
                                                    .attributeConverterProviders(CustomClassConverterProvider.create())
                                                    .json("{\"key\": \"Values\"}")
                                                    .build();

CustomClassForDocumentAPI customClass = documentFromJson.get("key", CustomClassForDocumentAPI.class)
Conclusion
In this blog post we showed you how to set up and begin using the Enhanced Document API with the DynamoDB Enhanced Client and standalone with the EnhancedDocument class. The enhanced client is open-source and resides in the same repository as the AWS SDK for Java 2.0. We hope you’ll find this new feature useful. You can always share your feedback on our GitHub issues page.
Email deliverability is a critical aspect of email as it directly impacts the success of campaigns by ensuring that messages reach the intended recipients’ inboxes. It encompasses factors like avoiding spam filters, maximizing open rates, and minimizing bounces. Companies often encounter deliverability problems due to various reasons, such as poor sender reputation, inadequate list hygiene, incorrect authentication, or engaging in spam-like behavior. Managing these problems can be challenging for companies because existing tools and techniques often fall short in addressing the ever-evolving email ecosystem. Factors such as evolving spam filters, complex email client algorithms, and constantly changing best practices necessitate continuous monitoring, optimization, and fine-tuning of email marketing strategies. Companies struggle to keep pace with these dynamic challenges and require advanced tools and expertise to effectively navigate deliverability obstacles.
Virtual deliverability manager (VDM) is an Amazon SES feature that helps you enhance email deliverability, like increasing inbox deliverability and email conversions, by providing insights into your sending and delivery data, and giving advice on how to fix the issues that are negatively affecting your delivery success rate and reputation. Virtual deliverability manager offers three components to help customers increase their email deliverability rates: deliverability insights, optimization recommendations, and detailed dashboards.
Visit this blog for details on the initial launch of virtual deliverability manager. After listening to our customers, we have added new features to virtual deliverability manager that this blog will address.
Graph & time view:
VDM now features a graph and time based view. The improvements in monitoring and diagnosing issues include the ability to view the data in graph form and with a timeline.
The new metrics pane displays VDM metrics as time series graphs with Volume progression on the left and Rate progression on the right. Hovering over a date interval in the graphs will show the exact volume count or rate percentage based on a daily aggregation. You can use the ‘select metrics’ dropdown menu to filter and choose the metrics you want to view.
Use case:
A time series graph displaying volume progression and rate progression can provide valuable insights to improve email deliverability for customers. Let’s consider a specific use case to illustrate this:
Use Case: Monitoring Engagement Metrics for Email Deliverability
Scenario: A business wants to enhance their email deliverability and ensure that their messages reach their subscribers’ inboxes. They are experiencing issues with low open rates and high spam complaints. To address these challenges, they decide to use a time series graph with volume progression and rate progression.
Implementation:
Volume Progression: By tracking the volume of emails sent over time, the business can observe any significant changes or spikes. A sudden increase in email volume might indicate a new marketing campaign or a change in email practices. Monitoring volume helps identify potential issues or anomalies that could impact deliverability. It allows businesses to correlate changes in volume with engagement metrics.
Rate Progression: Rate progression refers to tracking various engagement metrics over time, such as open rates, click-through rates, and unsubscribe rates. By analyzing these rates alongside email volume, the business can identify patterns or trends. For instance, a sudden drop in open rates may suggest that emails are landing in spam folders or being ignored by recipients. Conversely, a gradual increase in engagement rates indicates that emails are resonating with subscribers and likely to be delivered to their inboxes.
Benefits:
Early Detection of Issues: With a time series graph, businesses can detect delivery issues promptly. If a sudden drop in open rates or an increase in spam complaints is observed alongside a spike in email volume, it could indicate that the emails are being marked as spam or sent to the promotions tab. Identifying such issues early allows the business to take corrective measures, such as adjusting email content, optimizing subject lines, or reviewing their sender reputation.
Data-Driven Decision Making: By analyzing volume progression and rate progression, businesses gain valuable data to make informed decisions. They can assess the impact of changes in email strategies, content, or sending practices on deliverability. For instance, if a change in email design correlates with a decrease in open rates, the business can revert to a previous design or experiment with variations to optimize engagement.
Proactive Monitoring: By regularly monitoring volume and engagement metrics, businesses can proactively address potential deliverability issues. They can identify trends and take corrective action before they escalate. It enables businesses to maintain a positive sender reputation, improve email engagement, and optimize deliverability over time.
BIMI check in VDM Advisor:
Brand indicators for Message Identification (BIMI) is an email specification that enables email inboxes to display a brand’s logo next to the brand’s authenticated email messages within supported email clients. BIMI is an email specification that’s directly connected to authentication, but it’s not a standalone email authentication protocol as it requires all your email to comply with DMARC authentication.
While BIMI requires DMARC, DMARC requires your domain to have either SPF or DKIM records to align, however, it should be noted that both SPF and DKIM are recommended for best practice. Some email service providers (ESPs) require both when using BIMI. VDM’s Advisor now will let users know if BIMI records are not found or are not configured properly.
Breakdown by accounts, ISP, sending identity or config set:
Accounts: The VDM Account statistics table gives an overview of your deliverability and reputation metrics showing the total volume, rate percentage, and difference percentage for permanent/transient bounces, complaints, opens, clicks, sends, and delivered email.
ISP: You can now get these metrics by accounts, Internet Service Providers (ISP), sending identities and configuration sets. ISP specific data is important when you have a deliverability issue to a specific ISP or mailbox provider. Instead of trying to adjust your entire account which may otherwise be doing well, you can focus on the problematic endpoint and align with its best practices to improve sender reputation to that ISP and restore good inbox deliverability in order to reach your recipients.
Sending identities: Sending identity table shows the deliverability metrics like send volume, delivered, bounces (transient & permanent), complaints, opens & clicks, broken down by each sending identity.
When you can click on the sending identity, graphic cards will appear for the deliverability metrics and an ISP table will be displayed listing all the ISPs the sending identity sent mail to with bounce/complaint, open/click, and send/delivery rates given for each ISP within the date range entered.
Configuration sets: The Configuration sets table displays deliver rates for each configuration set that’s been used to send mail for the date range entered in the account overview panel. To get specific configuration set details, you can click on any configuration set to see its graphics card with deliverability details pertaining to that configuration set. The corresponding ISP table will be displayed listing all the ISPs the configuration set was used to send mail to with bounce/complaint, open/click, and send/delivery rates given for each ISP within the date range entered.
Conclusion:
By adding VDM to Amazon SES, now customers can gather greater insight into their deliverability through more granular deliverability metric aggregations, automated detection of deliverability configuration problems (with resolution instructions), and optimization of sending through high reputation channels.
About the author:
Vinay Ujjini is an Amazon Pinpoint and Amazon Simple Email Service Worldwide Principal Specialist Solutions Architect at AWS. He has been solving customer’s omni-channel challenges for over 15 years. He is an avid sports enthusiast and in his spare time, enjoys playing tennis & cricket.
In the world of email, sending emails over dedicated IPs can provide a number of benefits, including greater control over reputation and the ability to manage email deliverability. However, the heavy lifting involved in setting up and managing a dedicated IP can be intimidating, especially for those who are new to the process.
In this blog post, we’ll explain the benefits of using managed dedicated IPs from Amazon SES and how the new features, whether you’re a seasoned email professional or just getting started, will help take your email sending to the next level. Throughout the post, we’ll explain how managed dedicated IPs removes all of the heavy lifting of setting up, provisioning, monitoring and managing sending over dedicated IPS, how it helps ensure that IPs warm up efficiently, effectively and quickly, how you can get insights into how your IP Pool is performing, and how you can easily convert your current standard dedicated IPs to managed dedicated IPs. By the end of this post, you’ll have a solid understanding of the benefits of using a managed dedicated IPs for your email sending.
With the latest release of managed dedicated IPs, SES customers now have insights into the performance of their dedicated IPs, can easily convert their current dedicated IPs (standard) Pools into managed dedicated IP pools and can now create up to 50 dedicated IP pools.
What are managed dedicated IPs?
With standard IPs, users are provided an aggregate sending capacity, which is a combination of the capacity of all receiving Internet Service Providers (ISPs) such as Gmail, Yahoo, Outlook etc. However, each receiving ISP has a different capacity that depends on the reputation they assign to your dedicated IPs. For example, if you have a recipient list that consists of 800,000 individuals and your IP has a daily capacity of 1M emails. In this case you may assume that you have enough capacity to send all of your daily emails via your dedicated IP. However, the daily IP capacity may be made up of 400,000 of Gmail capacity and 600,000 of Yahoo capacity. If your recipient list consists of 500,000 Gmail addresses and 300,000 Yahoo addresses then your capacity on Yahoo is fine but you are over your capacity on Gmail and you will require another dedicated IP to manage your sending volume to Gmail. This is a simplistic example consisting of two major ISPs. Now consider how many different ISPs they are and how many different recipient email domains that your list consists of and you can easily see how complex this problem becomes. To solve this, many customer over-provision dedicated IPs i.e. they lease extra just in case they need the capacity. However, this approach doesn’t work as to build reputation (and capacity) on an IP you must send regularly and at a sufficient volume. You can’t just lease and hold a dedicated IP just in case you need it sometime.
With dedicated IP’s managed, your sending capacity is calculated at an ISP level, not at an aggregate level. What this means is that if your recipient list contains a large proportion of emails that get sent to a single ISP, then dedicated IPs managed will allocate you the optimal number of IPs to manage your sending capacity for that ISP. Customers don’t have to monitor the volume and manually calculate how many IPs they need to request, managed dedicated IPs does it all for you. When you need more IPs to manage your volume, managed dedicated IPs automatically provisions them, removing all of the heavy lifting and guesswork involved. And to give you insights into this, there is a range of metrics, accessible from within the SES console.
There are now two simple ways to get started with managed dedicated IPs. Users can just log on the AWS Console and load the configuration section of the SES Console. Select “Dedicated IPs”, and click “Enable dedicated IPs”.
If you have previously leased several standard dedicated IP addresses to use with Amazon SES, you would have created groups of those addresses, called dedicated IP pools. Grouping dedicated IPs together in a pool makes them easier to manage. A common scenario is to create one pool for sending marketing communications, and another for sending transactional emails. Your sender reputation for transactional emails is then isolated from that of your marketing emails. In this scenario, if a marketing campaign generates a large number of complaints, the delivery of your transactional emails is not impacted. If you already have dedicated IPs (standard) pools you can now convert these pools to managed IP pools in one click. Converting from a dedicated IP (standard) pool to a dedicated IP (managed) pool automatically transfers all of your standard IPs over to managed. So, you keep the same set of IPs, but you no longer have to worry about monitoring and managing them. You will no longer be charged per IP that you lease, but rather by the volume of emails that you send. For more information on pricing see the SES pricing page. There is one thing to be aware of before you switch; As managed dedicated IPs is optimized to allocate the number of IPs that you need for your sending volumes, if you have leased more dedicated IPs (standard) than you need then the redundant IPs will be removed. The only use case this may affect is where you have allowlisted specific dedicated IPs in downstream applications. You will need to be careful as managed dedicated IPs may automatically remove these IPs and you will no longer be sending emails from them. In this case, we recommend that you don’t switch to managed dedicated IPs.
How to create managed dedicated IPs
To create your dedicated IP (managed) pool, in Scaling mode select “Managed (auto managed)”, enter a name for your IP pool and associate it with a configuration set. Click ”Create Pool“ and your pool will be created. Previously, you could only create 5 managed dedicated IPs pools but with this release, you can now create 50 dedicated IP Pools (this can be 50 managed dedicated IPs pools or 50 dedicated IPs (standard) pools or a combination of both not exceeding 50).
Once you have created your pool you can access it from the Managed IP pools tab on the Dedicated IPs page. Once you have started to send email via your managed dedicated IPs pool then you can access metrics on the performance of your IPs. when you first start sending via managed dedicated IPs, your email volume will be split between your dedicated IPs and the shared SES IP pool. This is because when IPs are new, they have no reputation with receiving ISPs and therefore, have little capacity. Over time, receiving ISPs, based on variables such as the quality of content, the engagement rates, and your sending patterns, will increase capacity. If you try to send too much volume immediately via your dedicated IPs, receiving ISPs may flag this as a spam attempt and block, or throttle, the IP. managed dedicated IPs ensures that this will never happen by only sending the capacity that each receiving ISPs is willing to accept from the IPs and routes the excess to a shared IP pool to ensure that your email is still sent. This helps to build trust and quickly increase the capacity of the IPs, leading to a better reputation and quicker warm-up times. Over time, you will see a decrease in your email volume being sent via shared until all of it gets routed via dedicated IPs. Once your IPs are fully warmed up, if there is a spike in your email volume that exceeds the receiving ISP capacity, instead of routing the excess volume through shared, managed dedicated IPs will queue the excess volume and retry when there is capacity. This ensures that, when you have established reputation on your dedicated IPs, then all of your sending will be routed through them. You can easily see how much of your traffic is being sent via dedicated IPs versus how much is being routed through shared IPs in the Managed pool volume and Percentage of send volume via dedicated IPs metrics.
One of the key benefits of managed dedicated IPs is the ability to see your IP performance at an ISP level. Senders are able to see how much volume each ISP will accept from their IP pool. This helps to reassure that you are building reputation with the receiving ISPs and also gives you insights into the available contingent capacity should you have a sudden spike in volume. The ISP Capacity metric provides insights to your sent email volume versus the available capacity of the top 10 most popular ISPs.
Dedicated IPs (managed) is in all regions supported by SES. Visit the Amazon SES documentation for more information.
At Amazon Web Services (AWS), we strive to continuously improve customer experience by delivering a cloud computing environment that supports the most modern security technologies. To improve the overall performance of your connections, we have already started to enable TLS version 1.3 globally across our AWS service API endpoints, and will complete this process by December 31, 2023. By using TLS 1.3, you can decrease your connection time by removing one network round trip for every connection request, and can benefit from some of the most modern and secure cryptographic cipher suites available today.
If you are using current software tools (2014 or later) including our AWS SDKs or AWS Command Line Interface (AWS CLI), you will automatically receive the benefits of TLS 1.3 with no action required on your part. This is because AWS services will negotiate the highest TLS protocol version that your client software supports. If you want to continue using TLS 1.2, you will still have full control through your client configurations. AWS will retain support for TLS 1.2, in addition to TLS 1.3, into the foreseeable future. Meanwhile, here’s the latest information on the on-going deprecation of TLS 1.0/1.1.
If you have any questions, start a new thread on AWS re:Post, or contact AWS Support or your technical account manager. If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
RSA Conference 2023 brought thousands of cybersecurity professionals to the Moscone Center in San Francisco, California from April 24 through 27.
The keynote lineup was eclectic, with more than 30 presentations across two stages featuring speakers ranging from renowned theoretical physicist and futurist Dr. Michio Kaku to Grammy-winning musician Chris Stapleton. Topics aligned with this year’s conference theme, “Stronger Together,” and focused on actions that can be taken by everyone, from the C-suite to those of us on the front lines of security, to strengthen collaboration, establish new best practices, and make our defenses more diverse and effective.
With over 400 sessions and 500 exhibitors discussing the latest trends and technologies, it’s impossible to recap every highlight. Now that the dust has settled and we’ve had time to reflect, here’s a glimpse of what caught our attention.
We announced three new capabilities for our Amazon GuardDuty threat detection service to help customers secure container, database, and serverless workloads. These include GuardDuty Elastic Kubernetes Service (EKS) Runtime Monitoring, GuardDuty RDS Protection for data stored in Amazon Aurora, and GuardDuty Lambda Protection for serverless applications. The new capabilities are designed to provide actionable, contextual, and timely security findings with resource-specific details.
Artificial intelligence
It was hard to find a single keynote, session, or conversation that didn’t touch on the impact of artificial intelligence (AI).
In “AI: Law, Policy and Common Sense Suggestions on How to Stay Out of Trouble,” privacy and gaming attorney Behnam Dayanim highlighted ambiguity around the definition of AI. Referencing a quote from University of Washington School of Law’s Ryan Calo, Dayanim pointed out that AI may be best described as “…a set of techniques aimed at approximating some aspect of cognition,” and should therefore be thought of differently than a discrete “thing” or industry sector.
Dayanim noted examples of skepticism around the benefits of AI. A recent Monmouth University poll, for example, found that 73% of Americans believe AI will make jobs less available and harm the economy, and a surprising 55% believe AI may one day threaten humanity’s existence.
Equally skeptical, he noted, is a joint statement made by the Federal Trade Commission (FTC) and three other federal agencies during the conference reminding the public that enforcement authority applies to AI. The statement takes a pessimistic view, saying that AI is “…oftenadvertised as providing insights and breakthroughs, increasing efficiencies and cost-savings, and modernizing existing practices,” but has the potential to produce negative outcomes.
Dayanim covered existing and upcoming legal frameworks around the world that are aimed at addressing AI-related risks related to intellectual property (IP), misinformation, and bias, and how organizations can design AI governance mechanisms to promote fairness, competence, transparency, and accountability.
Many other discussions focused on the immense potential of AI to automate and improve security practices. RSA Security CEO Rohit Ghai explored the intersection of progress in AI with human identity in his keynote. “Access management and identity management are now table stakes features”, he said. In the AI era, we need an identity security solution that will secure the entire identity lifecycle—not just access. To be successful, he believes, the next generation of identity technology needs to be powered by AI, open and integrated at the data layer, and pursue a security-first approach. “Without good AI,” he said, “zero trust has zero chance.”
Mark Ryland, director at the Office of the CISO at AWS, spoke with Infosecurity about improving threat detection with generative AI.
“We’re very focused on meaningful data and minimizing false positives. And the only way to do that effectively is with machine learning (ML), so that’s been a core part of our security services,” he noted.
“Machine learning and artificial intelligence will add a critical layer of automation to cloud security. AI/ML will help augment developers’ workstreams, helping them create more reliable code and drive continuous security improvement. — CJ Moses, CISO and VP of security engineering at AWS
The human element
Dozens of sessions focused on the human element of security, with topics ranging from the psychology of DevSecOps to the NIST Phish Scale. In “How to Create a Breach-Deterrent Culture of Cybersecurity, from Board Down,” Andrzej Cetnarski, founder, chairman, and CEO of Cyber Nation Central and Marcus Sachs, deputy director for research at Auburn University, made a data-driven case for CEOs, boards, and business leaders to set a tone of security in their organizations, so they can address “cyber insecure behaviors that lead to social engineering” and keep up with the pace of cybercrime.
Lisa Plaggemier, executive director of the National Cybersecurity Alliance, and Jenny Brinkley, director of Amazon Security, stressed the importance of compelling security awareness training in “Engagement Through Entertainment: How To Make Security Behaviors Stick.” Education is critical to building a strong security posture, but as Plaggemier and Brinkley pointed out, we’re “living through an epidemic of boringness” in cybersecurity training.
According to a recent report, just 28% of employees say security awareness training is engaging, and only 36% say they pay full attention during such training.
Citing a United Airlines preflight safety video and Amazon’s Protect and Connect public service announcement (PSA) as examples, they emphasized the need to make emotional connections with users through humor and unexpected elements in order to create memorable training that drives behavioral change.
Plaggemeier and Brinkley detailed five actionable steps for security teams to improve their awareness training:
Brainstorm with staff throughout the company (not just the security people)
Find ideas and inspiration from everywhere else (TV episodes, movies… anywhere but existing security training)
Be relatable, and include insights that are relevant to your company and teams
Start small; you don’t need a large budget to add interest to your training
Don’t let naysayers deter you — change often prompts resistance
“You’ve got to make people care. And so you’ve got to find out what their personal motivators are, and how to develop the type of content that can make them care to click through the training and…remember things as they’re walking through an office.” — Jenny Brinkley, director of Amazon Security
Cloud security
Cloud security was another popular topic. In “Architecting Security for Regulated Workloads in Hybrid Cloud,” Mark Buckwell, cloud security architect at IBM, discussed the architectural thinking practices—including zero trust—required to integrate security and compliance into regulated workloads in a hybrid cloud environment.
Maor highlighted common tactics focused on identity theft, including MFA push fatigue, phishing, business email compromise, and adversary-in-the middle attacks. After detailing techniques that are used to establish persistence in SaaS environments and deliver ransomware, Maor emphasized the importance of forensic investigation and threat hunting to gaining the knowledge needed to reduce the impact of SaaS security incidents.
Sarah Currey, security practice manager, and Anna McAbee, senior solutions architect at AWS, provided complementary guidance in “Top 10 Ways to Evolve Cloud Native Incident Response Maturity.” Currey and McAbee highlighted best practices for addressing incident response (IR) challenges in the cloud — no matter who your provider is:
Define roles and responsibilities in your IR plan
Train staff on AWS (or your provider)
Develop cloud incident response playbooks
Develop account structure and tagging strategy
Run simulations (red team, purple team, tabletop)
Prepare access
Select and set up logs
Enable managed detection services in all available AWS Regions
Determine containment strategy for resource types
Develop cloud forensics capabilities
Speaking to BizTech, Clarke Rodgers, director of enterprise strategy at AWS, noted that tools and services such as Amazon GuardDuty and AWS Key Management Service (AWS KMS) are available to help advance security in the cloud. When organizations take advantage of these services and use partners to augment security programs, they can gain the confidence they need to take more risks, and accelerate digital transformation and product development.
Security takes a village
There are more highlights than we can mention on a variety of other topics, including post-quantum cryptography, data privacy, and diversity, equity, and inclusion. We’ve barely scratched the surface of RSA Conference 2023. If there is one key takeaway, it is that no single organization or individual can address cybersecurity challenges alone. By working together and sharing best practices as an industry, we can develop more effective security solutions and stay ahead of emerging threats.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
At AWS re:Invent 2022, we previewedAmazon SageMaker geospatial capabilities, allowing data scientists and machine learning (ML) engineers to build, train, and deploy ML models using geospatial data. Geospatial ML with Amazon SageMaker supports access to readily available geospatial data, purpose-built processing operations and open source libraries, pre-trained ML models, and built-in visualization tools with Amazon SageMaker’s geospatial capabilities.
During the preview, we had lots of interest and great feedback from customers. Today, Amazon SageMaker geospatial capabilities are generally available with new security updates and additional sample use cases.
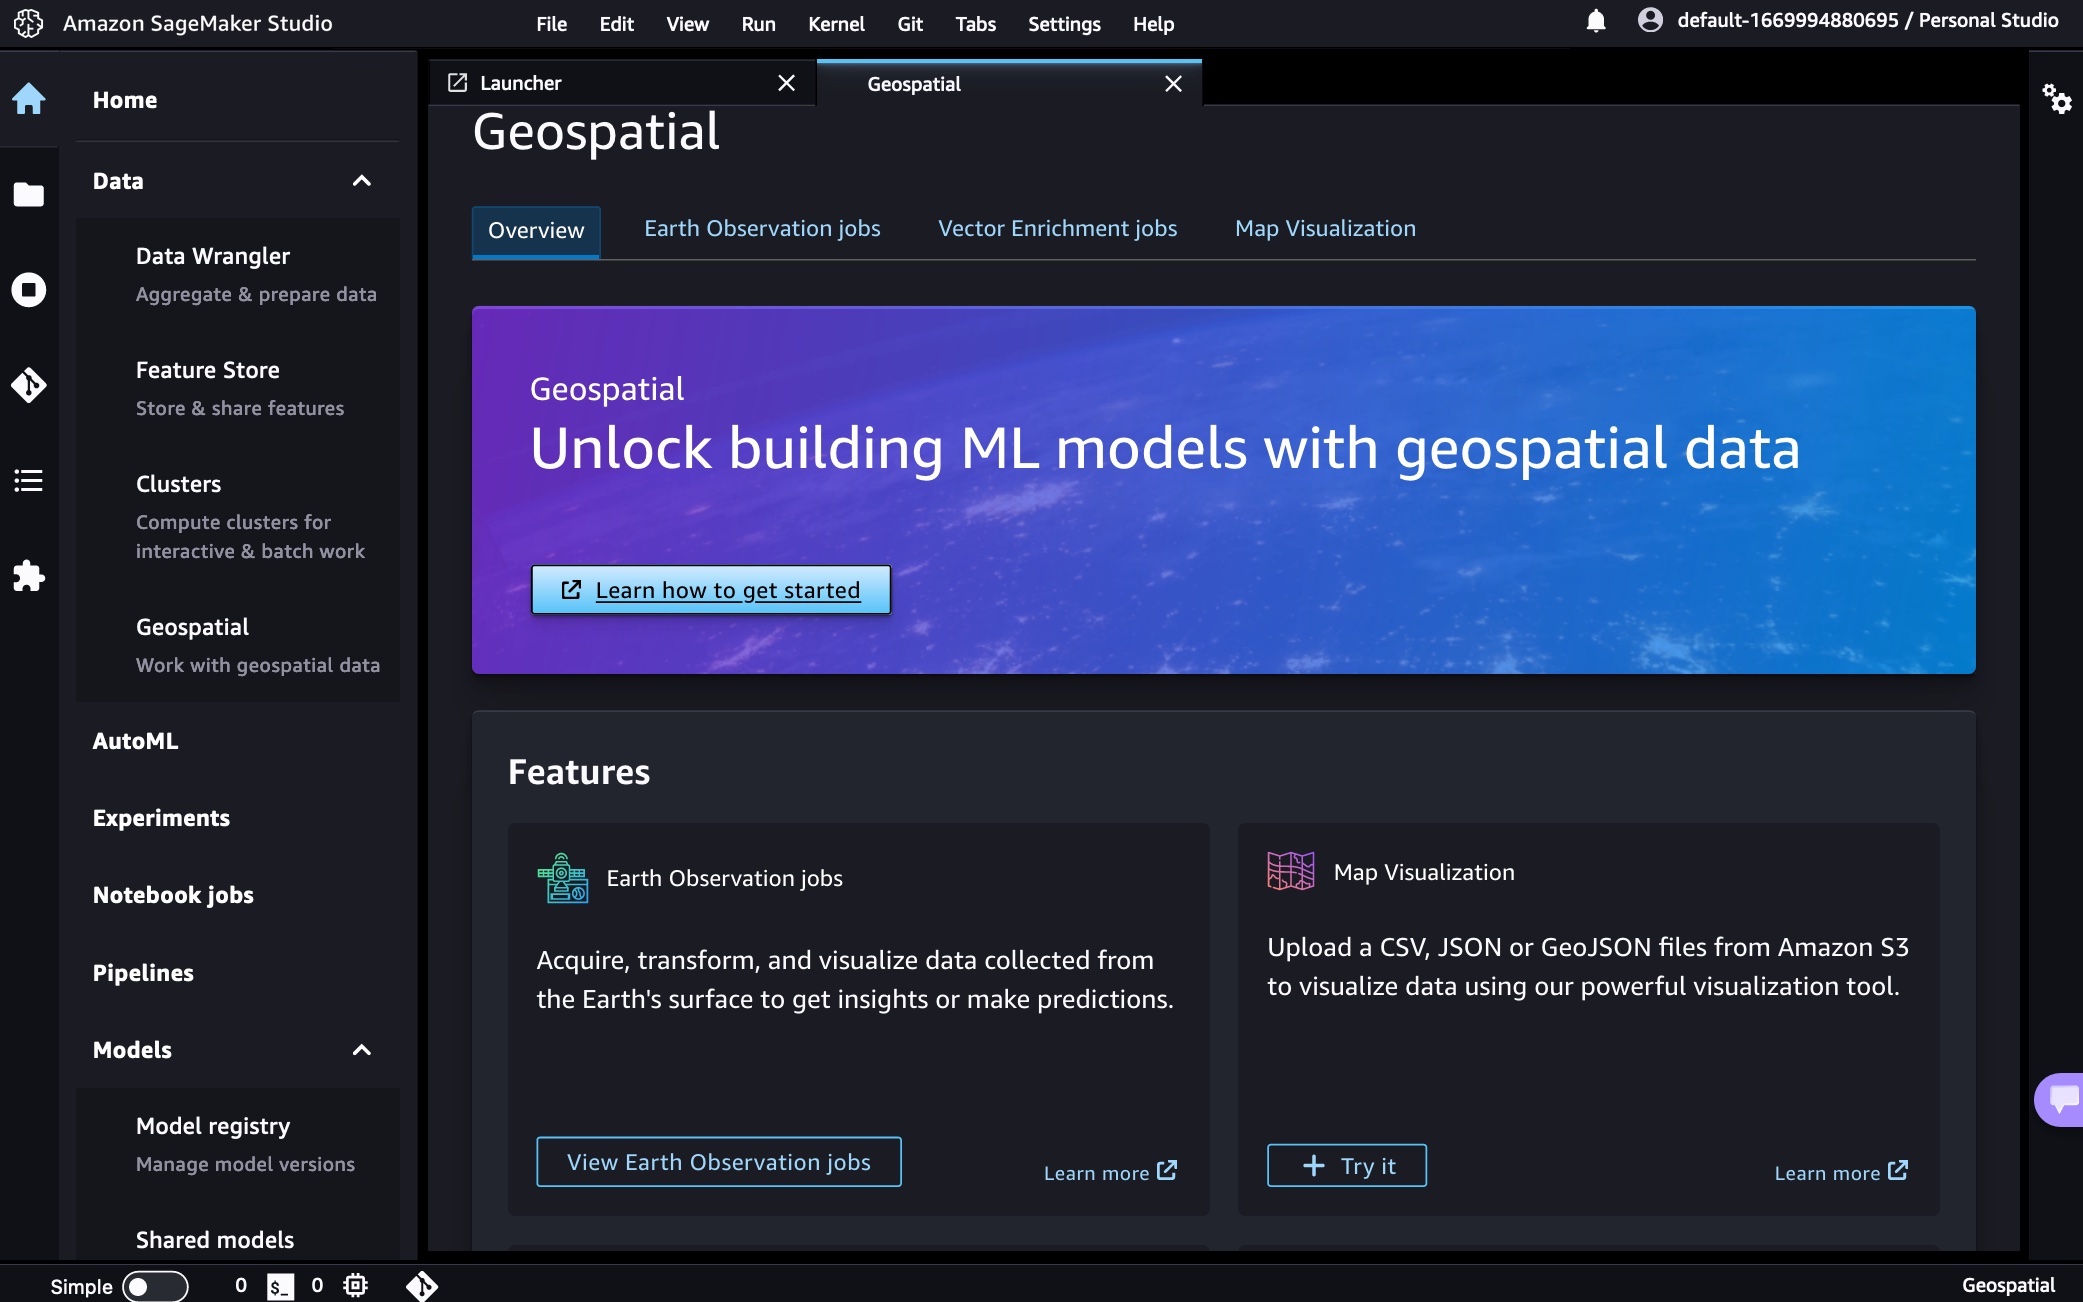
Introducing Geospatial ML features with SageMaker Studio To get started, use the quick setup to launch Amazon SageMaker Studio in the US West (Oregon) Region. Make sure to use the default Jupyter Lab 3 version when you create a new user in the Studio. Now you can navigate to the homepage in SageMaker Studio. Then select the Data menu and click on Geospatial.
Here is an overview of three key Amazon SageMaker geospatial capabilities:
Earth Observation jobs – Acquire, transform, and visualize satellite imagery data using purpose-built geospatial operations or pre-trained ML models to make predictions and get useful insights.
Vector Enrichment jobs – Enrich your data with operations, such as converting geographical coordinates to readable addresses.
Map Visualization – Visualize satellite images or map data uploaded from a CSV, JSON, or GeoJSON file.
You can create all Earth Observation Jobs (EOJ) in the SageMaker Studio notebook to process satellite data using purpose-built geospatial operations. Here is a list of purpose-built geospatial operations that are supported by the SageMaker Studio notebook:
Band Stacking – Combine multiple spectral properties to create a single image.
Cloud Masking – Identify cloud and cloud-free pixels to get improved and accurate satellite imagery.
Cloud Removal – Remove pixels containing parts of a cloud from satellite imagery.
Geomosaic – Combine multiple images for greater fidelity.
Land Cover Segmentation – Identify land cover types such as vegetation and water in satellite imagery.
Resampling – Scale images to different resolutions.
Spectral Index – Obtain a combination of spectral bands that indicate the abundance of features of interest.
Temporal Statistics – Calculate statistics through time for multiple GeoTIFFs in the same area.
Zonal Statistics – Calculate statistics on user-defined regions.
A Vector Enrichment Job (VEJ) enriches your location data through purpose-built operations for reverse geocoding and map matching. While you need to use a SageMaker Studio notebook to execute a VEJ, you can view all the jobs you create using the user interface. To use the visualization in the notebook, you first need to export your output to your Amazon S3 bucket.
Reverse Geocoding – Convert coordinates (latitude and longitude) to human-readable addresses.
Map Matching – Snap inaccurate GPS coordinates to road segments.
Using the Map Visualization, you can visualize geospatial data, the inputs to your EOJ or VEJ jobs as well as the outputs exported from your Amazon Simple Storage Service (Amazon S3) bucket.
Security Updates At GA, we have two major security updates—AWS Key Management Service (AWS KMS) for customer managed AWS KMS key support and Amazon Virtual Private Cloud (Amazon VPC) for geospatial operations in the customer Amazon VPC environment.
AWS KMS customer managed keys offer increased flexibility and control by enabling customers to use their own keys to encrypt geospatial workloads.
You can use KmsKeyId to specify your own key in StartEarthObservationJob and StartVectorEnrichmentJob as an optional parameter. If the customer doesn’t provide KmsKeyId, a service owned key will be used to encrypt the customer content. To learn more, see SageMaker geospatial capabilities AWS KMS Support in the AWS documentation.
Using Amazon VPC, you have full control over your network environment and can more securely connect to your geospatial workloads on AWS. You can use SageMaker Studio or Notebook in your Amazon VPC environment for SageMaker geospatial operations and execute SageMaker geospatial API operations through an interface VPC endpoint in SageMaker geospatial operations.
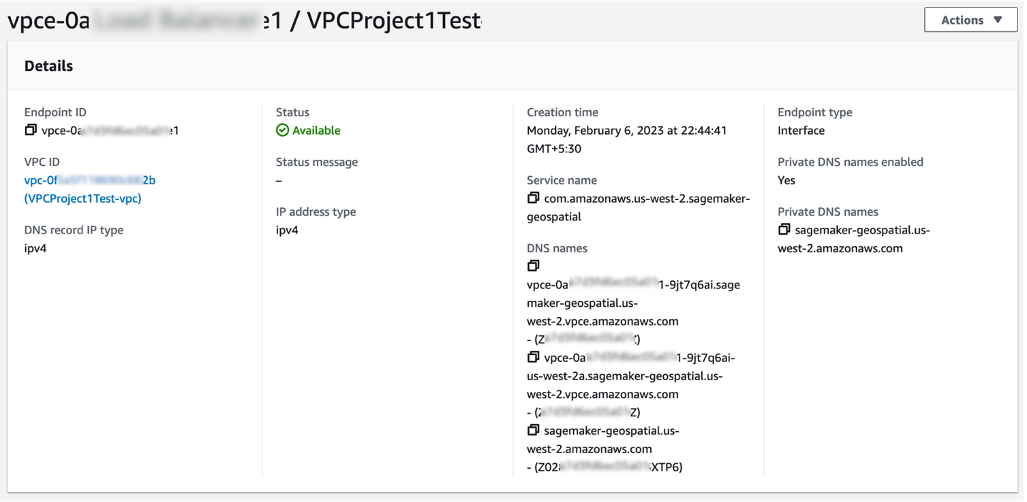
To get started with Amazon VPC support, configure Amazon VPC on SageMaker Studio Domain and create a SageMaker geospatial VPC endpoint in your VPC in the Amazon VPC console. Choose the service name as com.amazonaws.us-west-2.sagemaker-geospatial and select the VPC in which to create the VPC endpoint.
All Amazon S3 resources that are used for input or output in EOJ and VEJ operations should have internet access enabled. If you have no direct access to those Amazon S3 resources via the internet, you can grant SageMaker geospatial VPC endpoint ID access to it by changing the corresponding S3 bucket policy. To learn more, see SageMaker geospatial capabilities Amazon VPC Support in the AWS documentation.
Example Use Case for Geospatial ML Customers across various industries use Amazon SageMaker geospatial capabilities for real-world applications.
Maximize Harvest Yield and Food Security Digital farming consists of applying digital solutions to help farmers optimize crop production in agriculture through the use of advanced analytics and machine learning. Digital farming applications require working with geospatial data, including satellite imagery of the areas where farmers have their fields located.
Damage Assessment As the frequency and severity of natural disasters increase, it’s important that we equip decision-makers and first responders with fast and accurate damage assessment. You can use geospatial imagery to predict natural disaster damage and geospatial data in the immediate aftermath of a natural disaster to rapidly identify damage to buildings, roads, or other critical infrastructure.
From an example notebook, you can train, deploy, and predict natural disaster damage from the floods in Rochester, Australia, in mid-October 2022. We use images from before and after the disaster as input to its trained ML model. The results of the segmentation mask for the Rochester floods are shown in the following images. Here we can see that the model has identified locations within the flooded region as likely damaged.
You can train and deploy a geospatial segmentation model to assess wildfire damages using multi-temporal Sentinel-2 satellite data via GitHub repository. The area of interest for this example is located in Northern California, from a region that was affected by the Dixie Wildfire in 2021.
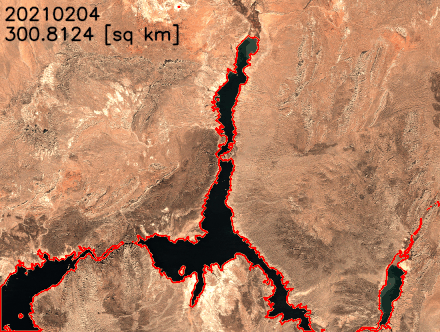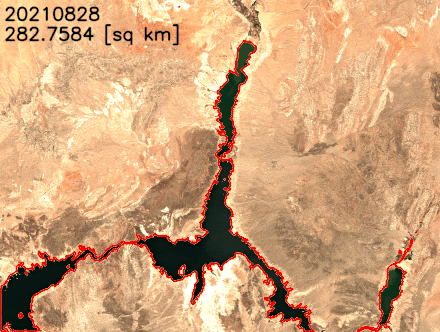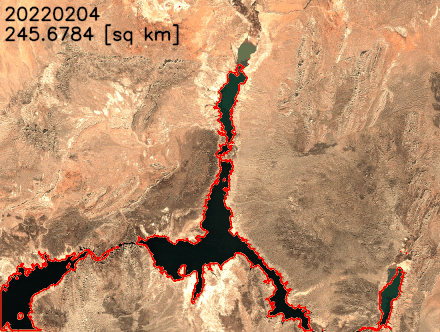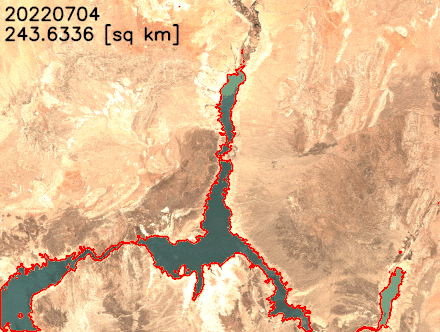
Monitor Climate Change Earth’s climate change increases the risk of drought due to global warming. You can see how to acquire data, perform analysis, and visualize the changes with SageMaker geospatial capabilities to monitor shrinking shoreline caused by climate change in the Lake Mead example, the largest reservoir in the US.
You can find the notebook code for this example in the GitHub repository.
Predict Retail Demand The new notebook example demonstrates how to use SageMaker geospatial capabilities to perform a vector-based map-matching operation and visualize the results. Map matching allows you to snap noisy GPS coordinates to road segments. With Amazon SageMaker geospatial capabilities, it is possible to perform a VEJ for map matching. This type of job takes a CSV file with route information (such as longitude, latitude, and timestamps of GPS measurements) as input and produces a GeoJSON file that contains the predicted route.
Support Sustainable Urban Development Arup, one of our customers, uses digital technologies like machine learning to explore the impact of heat on urban areas and the factors that influence local temperatures to deliver better design and support sustainable outcomes. Urban Heat Islands and the associated risks and discomforts are one of the biggest challenges cities are facing today.
Using Amazon SageMaker geospatial capabilities, Arup identifies and measures urban heat factors with earth observation data, which significantly accelerated their ability to counsel clients. It enabled its engineering teams to carry out analytics that weren’t possible previously by providing access to increased volumes, types, and analysis of larger datasets. To learn more, see Facilitating Sustainable City Design Using Amazon SageMaker with Arup in AWS customer stories.
Now Available Amazon SageMaker geospatial capabilities are now generally available in the US West (Oregon) Region. As part of the AWS Free Tier, you can get started with SageMaker geospatial capabilities for free. The Free Tier lasts 30 days and includes 10 free ml.geospatial.interactive compute hours, up to 10 GB of free storage, and no $150 monthly user fee.
After the 30-day free trial period is complete, or if you exceed the Free Tier limits defined above, you pay for the components outlined on the pricing page.
With Amazon Detective, you can analyze and visualize security data to investigate potential security issues. Detective collects and analyzes events that describe IP traffic, AWS management operations, and malicious or unauthorized activity from AWS CloudTrail logs, Amazon Virtual Private Cloud (Amazon VPC)Flow Logs, Amazon GuardDuty findings, and, since last year, Amazon Elastic Kubernetes Service (EKS) audit logs. Using this data, Detective constructs a graph model that distills log data using machine learning, statistical analysis, and graph theory to build a linked set of data for your security investigations.
Starting today, Detective offers investigation support for findings in AWS Security Hub in addition to those detected by GuardDuty. Security Hub is a service that provides you with a view of your security state in AWS and helps you check your environment against security industry standards and best practices. If you’ve turned on Security Hub and another integrated AWS security services, those services will begin sending findings to Security Hub.
Enabling AWS Security Findings in the Amazon Detective Console When you enable Detective for the first time, Detective now identifies findings coming from both GuardDuty and Security Hub, and automatically starts ingesting them along with other data sources. Note that you don’t need to enable or publish these log sources for Detective to start its analysis because this is managed directly by Detective.
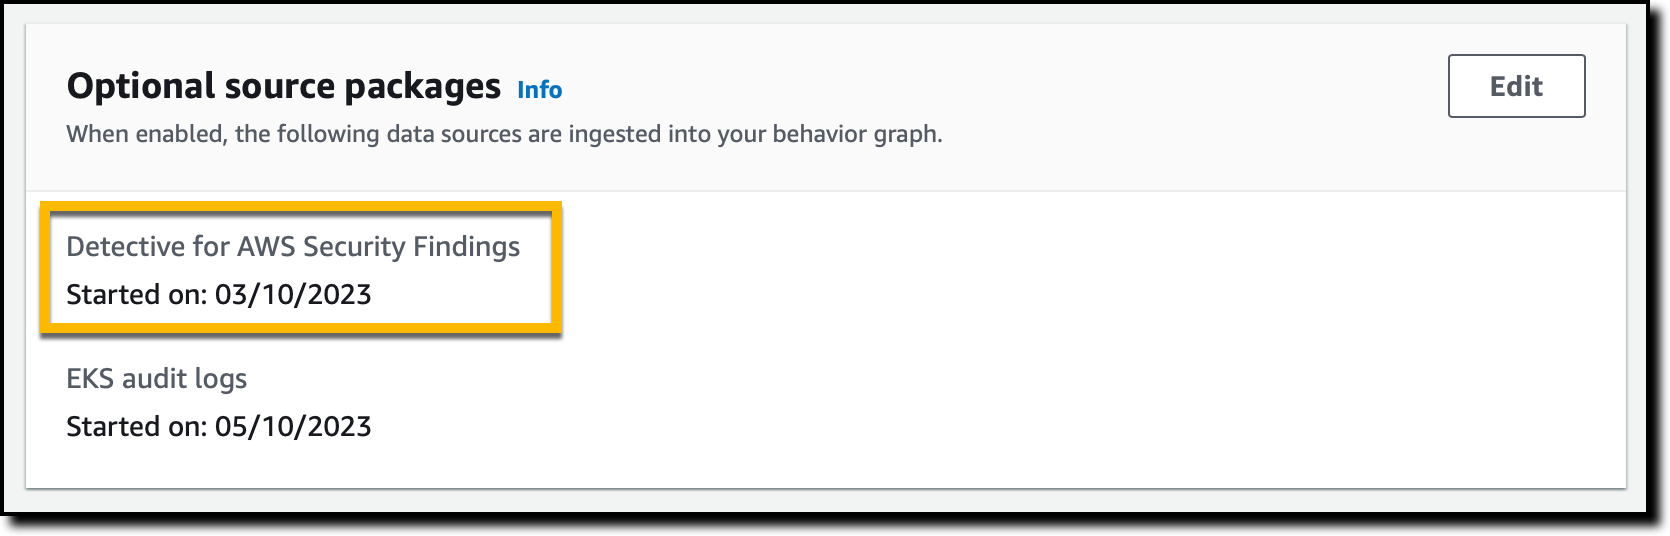
If you are an existing Detective customer, you can enable investigation of AWS Security Findings as a data source with one click in the Detective Management Console. I already have Detective enabled, so I add the source package.
In the Detective console, in the Settings section of the navigation pane, I choose General. There, I choose Edit in the Optional source packages section to enable Detective for AWS Security Findings.
Once enabled, Detective starts analyzing all the relevant data to identify connections between disparate events and activities. To start your investigation process, you can get a visualization of these connections, including resource behavior and activities. Historical baselines, which you can use to provide comparisons against recent activity, are established after two weeks.
Investigating AWS Security Findings in the Amazon Detective Console I start in the Security Hub console and choose Findings in the navigation pane. There, I filter findings to only see those where the Product name is Inspector and Severity label is HIGH.
The first one looks suspicious, so I choose its Title (CVE-2020-36223 – openldap). The Security Hub console provides me with information about the corresponding Common Vulnerabilities and Exposures (CVE) ID and where and how it was found. At the bottom, I have the option to Investigate in Amazon Detective. I follow the Investigate finding link, and the Detective console opens in another browser tab.
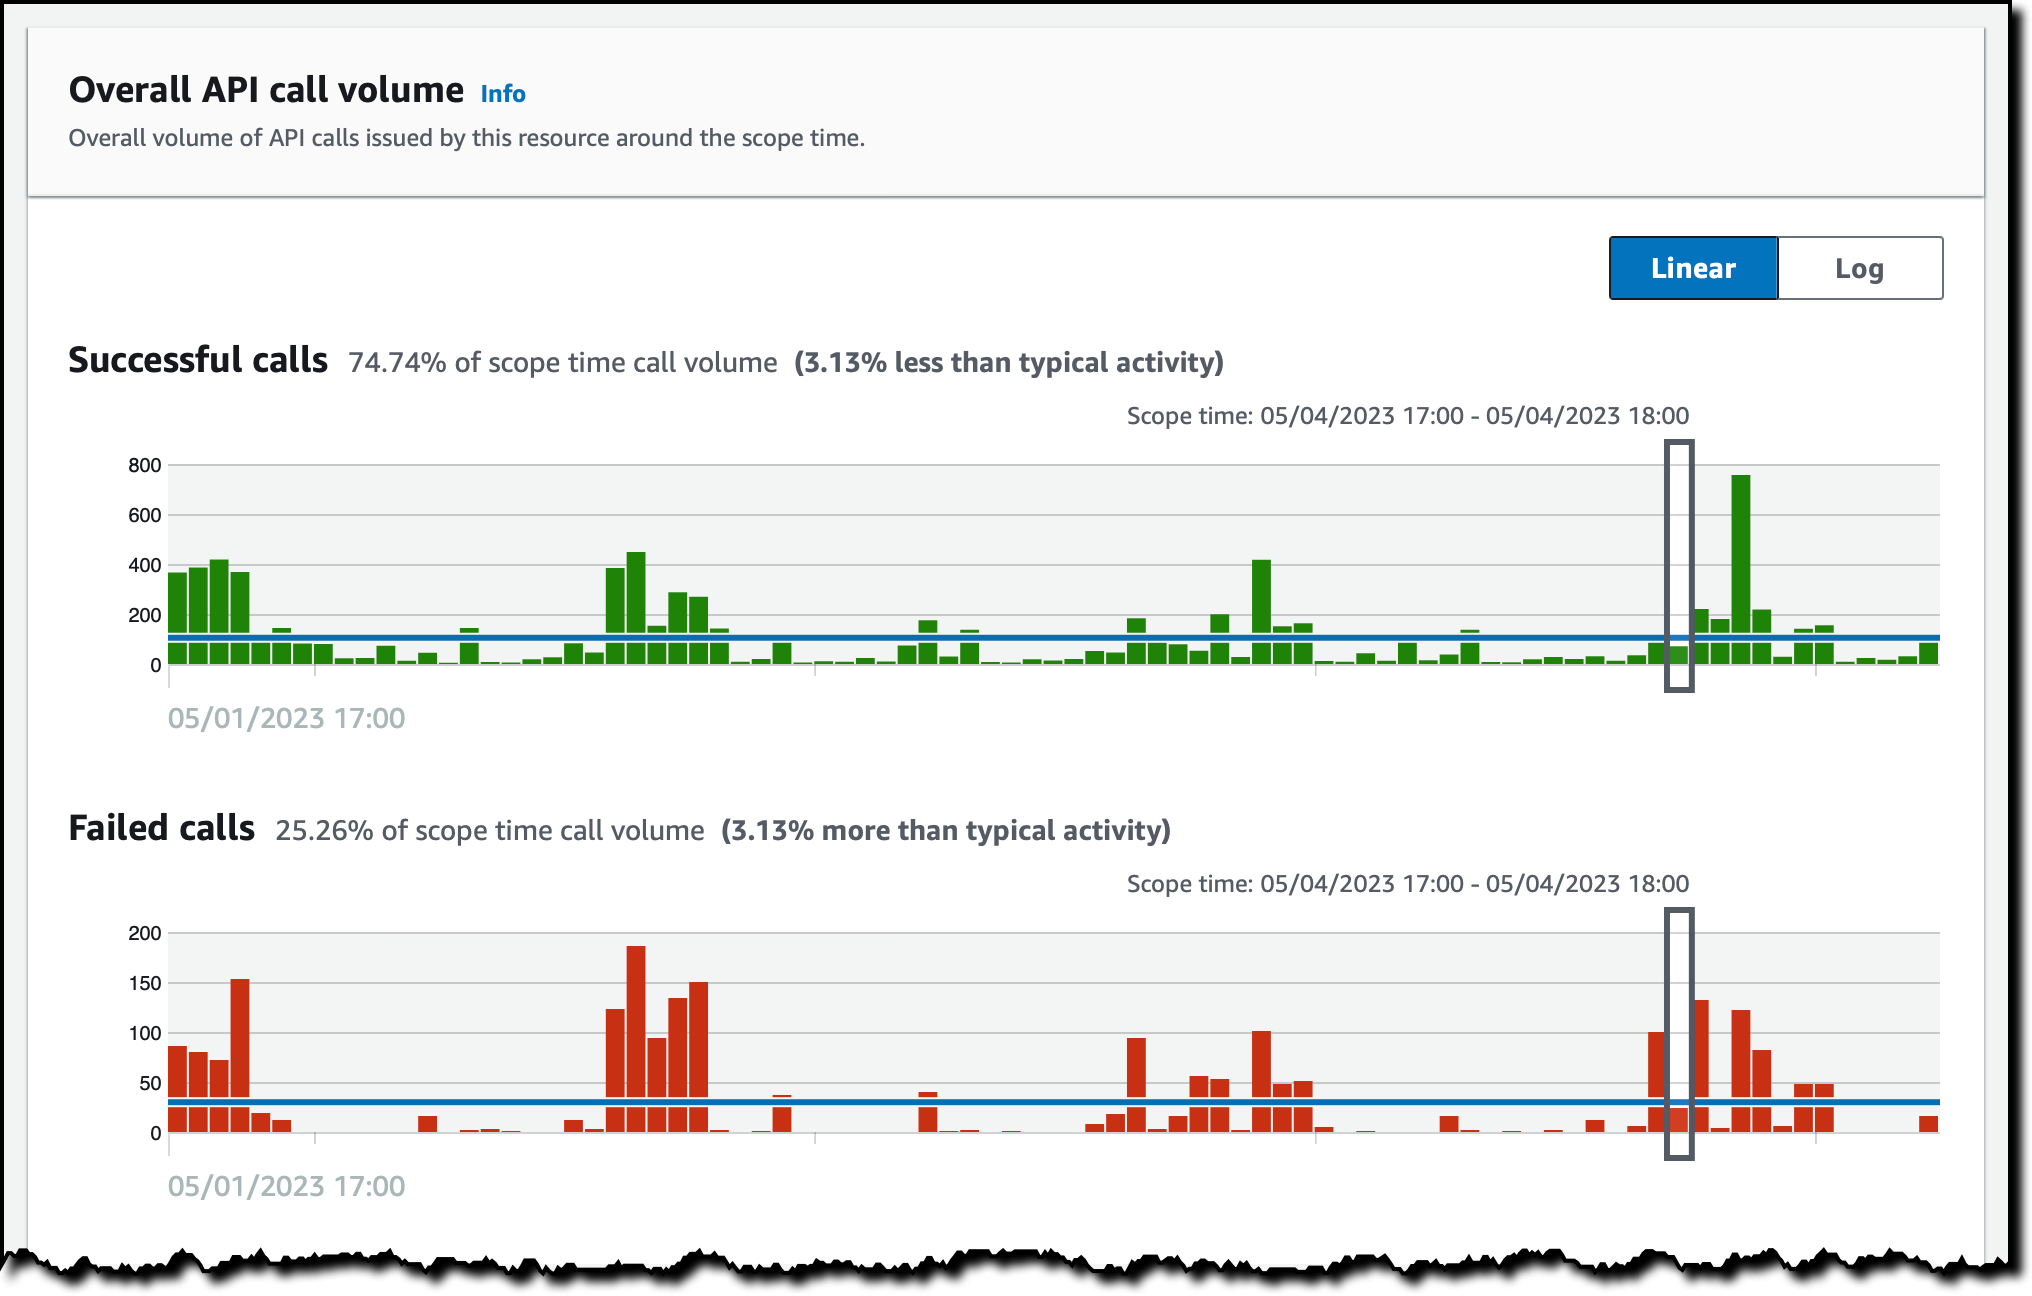
Here, I see the entities related to this Inspector finding. First, I open the profile of the AWS account to see all the findings associated with this resource, the overall API call volume issued by this resource, and the container clusters in this account.
For example, I look at the successful and failed API calls to have a better understanding of the impact of this finding.
Then, I open the profile for the container image. There, I see the images that are related to this image (because they have the same repository or registry as this image), the containers running from this image during the scope time (managed by Amazon EKS), and the findings associated with this resource.
Depending on the finding, Detective helps me correlate information from different sources such as CloudTrail logs, VPC Flow Logs, and EKS audit logs. This information makes it easier to understand the impact of the finding and if the risk has become an incident. For Security Hub, Detective only ingests findings for configuration checks that failed. Because configuration checks that passed have little security value, we’re filtering these outs.
Availability and Pricing Amazon Detective investigation support for AWS Security Findings is available today for all existing and new Detective customers in all AWS Regions where Detective is available, including the AWS GovCloud (US) Regions. For more information, see the AWS Regional Services List.
Amazon Detective is priced based on the volume of data ingested. By enabling investigation of AWS Security Findings, you can increase the volume of ingested data. For more information, see Amazon Detective pricing.
When GuardDuty and Security Hub provide a finding, they also suggest the remediation. On top of that, Detective helps me investigate if the vulnerability has been exploited, for example, using logs and network traffic as proof.
Currently, findings coming from Security Hub are not included in the Finding groups section of the Detective console. Our plan is to expand Finding groups to cover the newly integrated AWS security services. Stay tuned!
A full conference pass is $1,099. Register today with the code secure150off to receive a limited time $150 discount, while supplies last.
AWS re:Inforce is back, and we can’t wait to welcome security builders to Anaheim, CA, on June 13 and 14. AWS re:Inforce is a security learning conference where you can gain skills and confidence in cloud security, compliance, identity, and privacy. As an attendee, you will have access to hundreds of technical and non-technical sessions, an Expo featuring AWS experts and security partners with AWS Security Competencies, and keynote and leadership sessions featuring Security leadership. re:Inforce 2023 features content across the following six areas:
Data protection
Governance, risk, and compliance
Identity and access management
Network and infrastructure security
Threat detection and incident response
Application security
The threat detection and incident response track is designed to showcase how AWS, customers, and partners can intelligently detect potential security risks, centralize and streamline security management at scale, investigate and respond quickly to security incidents across their environment, and unlock security innovation across hybrid cloud environments.
Breakout sessions, chalk talks, and lightning talks
TDR201 | Breakout session | How Citi advanced their containment capabilities through automation Incident response is critical for maintaining the reliability and security of AWS environments. To support the 28 AWS services in their cloud environment, Citi implemented a highly scalable cloud incident response framework specifically designed for their workloads on AWS. Using AWS Step Functions and AWS Lambda, Citi’s automated and orchestrated incident response plan follows NIST guidelines and has significantly improved its response time to security events. In this session, learn from real-world scenarios and examples on how to use AWS Step Functions and other core AWS services to effectively build and design scalable incident response solutions.
TDR202 | Breakout session | Wix’s layered security strategy to discover and protect sensitive data Wix is a leading cloud-based development platform that empowers users to get online with a personalized, professional web presence. In this session, learn how the Wix security team layers AWS security services including Amazon Macie, AWS Security Hub, and AWS Identity and Access Management Access Analyzer to maintain continuous visibility into proper handling and usage of sensitive data. Using AWS security services, Wix can discover, classify, and protect sensitive information across terabytes of data stored on AWS and in public clouds as well as SaaS applications, while empowering hundreds of internal developers to drive innovation on the Wix platform.
TDR203 | Breakout session | Vulnerability management at scale drives enterprise transformation Automating vulnerability management at scale can help speed up mean time to remediation and identify potential business-impacting issues sooner. In this session, explore key challenges that organizations face when approaching vulnerability management across large and complex environments, and consider the innovative solutions that AWS provides to help overcome them. Learn how customers use AWS services such as Amazon Inspector to automate vulnerability detection, streamline remediation efforts, and improve compliance posture. Whether you’re just getting started with vulnerability management or looking to optimize your existing approach, gain valuable insights and inspiration to help you drive innovation and enhance your security posture with AWS.
TDR204 | Breakout session | Continuous innovation in AWS detection and response services Join this session to learn about the latest advancements and most recent AWS launches in detection and response. This session focuses on use cases such as automated threat detection, continual vulnerability management, continuous cloud security posture management, and unified security data management. Through these examples, gain a deeper understanding of how you can seamlessly integrate AWS services into your existing security framework to gain greater control and insight, quickly address security risks, and maintain the security of your AWS environment.
TDR205 | Breakout session | Build your security data lake with Amazon Security Lake, featuring Interpublic Group Security teams want greater visibility into security activity across their entire organizations to proactively identify potential threats and vulnerabilities. Amazon Security Lake automatically centralizes security data from cloud, on-premises, and custom sources into a purpose-built data lake stored in your account and allows you to use industry-leading AWS and third-party analytics and ML tools to gain insights from your data and identify security risks that require immediate attention. Discover how Security Lake can help you consolidate and streamline security logging at scale and speed, and hear from an AWS customer, Interpublic Group (IPG), on their experience.
TDR209 | Breakout session | Centralizing security at scale with Security Hub & Intuit’s experience As organizations move their workloads to the cloud, it becomes increasingly important to have a centralized view of security across their cloud resources. AWS Security Hub is a powerful tool that allows organizations to gain visibility into their security posture and compliance status across their AWS accounts and Regions. In this session, learn about Security Hub’s new capabilities that help simplify centralizing and operationalizing security. Then, hear from Intuit, a leading financial software company, as they share their experience and best practices for setting up and using Security Hub to centralize security management.
TDR210 | Breakout session | Streamline security analysis with Amazon Detective Join us to discover how to streamline security investigations and perform root-cause analysis with Amazon Detective. Learn how to leverage the graph analysis techniques in Detective to identify related findings and resources and investigate them together to accelerate incident analysis. Also hear a customer story about their experience using Detective to analyze findings automatically ingested from Amazon GuardDuty, and walk through a sample security investigation.
TDR310 | Breakout session | Developing new findings using machine learning in Amazon GuardDuty Amazon GuardDuty provides threat detection at scale, helping you quickly identify and remediate security issues with actionable insights and context. In this session, learn how GuardDuty continuously enhances its intelligent threat detection capabilities using purpose-built machine learning models. Discover how new findings are developed for new data sources using novel machine learning techniques and how they are rigorously evaluated. Get a behind-the-scenes look at GuardDuty findings from ideation to production, and learn how this service can help you strengthen your security posture.
TDR311 | Breakout session | Securing data and democratizing the alert landscape with an event-driven architecture Security event monitoring is a unique challenge for businesses operating at scale and seeking to integrate detections into their existing security monitoring systems while using multiple detection tools. Learn how organizations can triage and raise relevant cloud security findings across a breadth of detection tools and provide results to downstream security teams in a serverless manner at scale. We discuss how to apply a layered security approach to evaluate the security posture of your data, protect your data from potential threats, and automate response and remediation to help with compliance requirements.
TDR231 | Chalk talk | Operationalizing security findings at scale You enabled AWS Security Hub standards and checks across your AWS organization and in all AWS Regions. What should you do next? Should you expect zero critical and high findings? What is your ideal state? Is achieving zero findings possible? In this chalk talk, learn about a framework you can implement to triage Security Hub findings. Explore how this framework can be applied to several common critical and high findings, and take away mechanisms to prioritize and respond to security findings at scale.
TDR232 | Chalk talk | Act on security findings using Security Hub’s automation capabilities Alert fatigue, a shortage of skilled staff, and keeping up with dynamic cloud resources are all challenges that exist when it comes to customers successfully achieving their security goals in AWS. In order to achieve their goals, customers need to act on security findings associated with cloud-based resources. In this session, learn how to automatically, or semi-automatically, act on security findings aggregated in AWS Security Hub to help you secure your organization’s cloud assets across a diverse set of accounts and Regions.
TDR233 | Chalk talk | How LLA reduces incident response time with AWS Systems Manager Liberty Latin America (LLA) is a leading telecommunications company operating in over 20 countries across Latin America and the Caribbean. LLA offers communications and entertainment services, including video, broadband internet, telephony, and mobile services. In this chalk talk, discover how LLA implemented a security framework to detect security issues and automate incident response in more than 180 AWS accounts accessed by internal stakeholders and third-party partners using AWS Systems Manager Incident Manager, AWS Organizations, Amazon GuardDuty, and AWS Security Hub.
TDR432 | Chalk talk | Deep dive into exposed credentials and how to investigate them In this chalk talk, sharpen your detection and investigation skills to spot and explore common security events like unauthorized access with exposed credentials. Learn how to recognize the indicators of such events, as well as logs and techniques that unauthorized users use to evade detection. The talk provides knowledge and resources to help you immediately prepare for your own security investigations.
TDR332 | Chalk talk | Speed up zero-day vulnerability response In this chalk talk, learn how to scale vulnerability management for Amazon EC2 across multiple accounts and AWS Regions. Explore how to use Amazon Inspector, AWS Systems Manager, and AWS Security Hub to respond to zero-day vulnerabilities, and leave knowing how to plan, perform, and report on proactive and reactive remediations.
TDR333 | Chalk talk | Gaining insights from Amazon Security Lake You’ve created a security data lake, and you’re ingesting data. Now what? How do you use that data to gain insights into what is happening within your organization or assist with investigations and incident response? Join this chalk talk to learn how analytics services and security information and event management (SIEM) solutions can connect to and use data stored within Amazon Security Lake to investigate security events and identify trends across your organization. Leave with a better understanding of how you can integrate Amazon Security Lake with other business intelligence and analytics tools to gain valuable insights from your security data and respond more effectively to security events.
TDR431 | Chalk talk | The anatomy of a ransomware event Ransomware events can cost governments, nonprofits, and businesses billions of dollars and interrupt operations. Early detection and automated responses are important steps that can limit your organization’s exposure. In this chalk talk, examine the anatomy of a ransomware event that targets data residing in Amazon RDS and get detailed best practices for detection, response, recovery, and protection.
TDR221 | Lightning talk | Streamline security operations and improve threat detection with OCSF Security operations centers (SOCs) face significant challenges in monitoring and analyzing security telemetry data from a diverse set of sources. This can result in a fragmented and siloed approach to security operations that makes it difficult to identify and investigate incidents. In this lightning talk, get an introduction to the Open Cybersecurity Schema Framework (OCSF) and its taxonomy constructs, and see a quick demo on how this normalized framework can help SOCs improve the efficiency and effectiveness of their security operations.
TDR222 | Lightning talk | Security monitoring for connected devices across OT, IoT, edge & cloud With the responsibility to stay ahead of cybersecurity threats, CIOs and CISOs are increasingly tasked with managing cybersecurity risks for their connected devices including devices on the operational technology (OT) side of the company. In this lightning talk, learn how AWS makes it simpler to monitor, detect, and respond to threats across the entire threat surface, which includes OT, IoT, edge, and cloud, while protecting your security investments in existing third-party security tools.
TDR223 | Lightning talk | Bolstering incident response with AWS Wickr enterprise integrations Every second counts during a security event. AWS Wickr provides end-to-end encrypted communications to help incident responders collaborate safely during a security event, even on a compromised network. Join this lightning talk to learn how to integrate AWS Wickr with AWS security services such as Amazon GuardDuty and AWS WAF. Learn how you can strengthen your incident response capabilities by creating an integrated workflow that incorporates GuardDuty findings into a secure, out-of-band communication channel for dedicated teams.
TDR224 | Lightning talk | Securing the future of mobility: Automotive threat modeling Many existing automotive industry cybersecurity threat intelligence offerings lack the connected mobility insights required for today’s automotive cybersecurity threat landscape. Join this lightning talk to learn about AWS’s approach to developing an automotive industry in-vehicle, domain-specific threat intelligence solution using AWS AI/ML services that proactively collect, analyze, and deduce threat intelligence insights for use and adoption across automotive value chains.
Hands-on sessions (builders’ sessions and workshops)
TDR251 | Builders’ session | Streamline and centralize security operations with AWS Security Hub AWS Security Hub provides you with a comprehensive view of the security state of your AWS resources by collecting security data from across AWS accounts, Regions, and services. In this builders’ session, explore best practices for using Security Hub to manage security posture, prioritize security alerts, generate insights, automate response, and enrich findings. Come away with a better understanding of how to use Security Hub features and practical tips for getting the most out of this powerful service.
TDR351 | Builders’ session | Broaden your scope: Analyze and investigate potential security issues In this builders’ session, learn how you can more efficiently triage potential security issues with a dynamic visual representation of the relationship between security findings and associated entities such as accounts, IAM principals, IP addresses, Amazon S3 buckets, and Amazon EC2 instances. With Amazon Detective finding groups, you can group related Amazon GuardDuty findings to help reduce time spent in security investigations and in understanding the scope of a potential issue. Leave this hands-on session knowing how to quickly investigate and discover the root cause of an incident.
TDR352 | Builders’ session | How to automate containment and forensics for Amazon EC2 In this builders’ session, learn how to deploy and scale the self-service Automated Forensics Orchestrator for Amazon EC2 solution, which gives you a standardized and automated forensics orchestration workflow capability to help you respond to Amazon EC2 security events. Explore the prerequisites and ways to customize the solution to your environment.
TDR353 | Builders’ session | Detecting suspicious activity in Amazon S3 Have you ever wondered how to uncover evidence of unauthorized activity in your AWS account? In this builders’ session, join the AWS Customer Incident Response Team (CIRT) for a guided simulation of suspicious activity within an AWS account involving unauthorized data exfiltration and Amazon S3 bucket and object data deletion. Learn how to detect and respond to this malicious activity using AWS services like AWS CloudTrail, Amazon Athena, Amazon GuardDuty, Amazon CloudWatch, and nontraditional threat detection services like AWS Billing to uncover evidence of unauthorized use.
TDR354 | Builders’ session | Simulate and detect unwanted IMDS access due to SSRF Using appropriate security controls can greatly reduce the risk of unauthorized use of web applications. In this builders’ session, find out how the server-side request forgery (SSRF) vulnerability works, how unauthorized users may try to use it, and most importantly, how to detect it and prevent it from being used to access the instance metadata service (IMDS). Also, learn some of the detection activities that the AWS Customer Incident Response Team (CIRT) performs when responding to security events of this nature.
TDR341 | Code talk | Investigating incidents with Amazon Security Lake & Jupyter notebooks In this code talk, watch as experts live code and build an incident response playbook for your AWS environment using Jupyter notebooks, Amazon Security Lake, and Python code. Leave with a better understanding of how to investigate and respond to a security event and how to use these technologies to more effectively and quickly respond to disruptions.
TDR441 | Code talk | How to run security incident response in your Amazon EKS environment Join this Code Talk to get both an adversary’s and a defender’s point of view as AWS experts perform live exploitation of an application running on multiple Amazon EKS clusters, invoking an alert in Amazon GuardDuty. Experts then walk through incident response procedures to detect, contain, and recover from the incident in near real-time. Gain an understanding of how to respond and recover to Amazon EKS-specific incidents as you watch the events unfold.
TDR271-R | Workshop | Chaos Kitty: Gamifying incident response with chaos engineering When was the last time you simulated an incident? In this workshop, learn to build a sandbox environment to gamify incident response with chaos engineering. You can use this sandbox to test out detection capabilities, play with incident response runbooks, and illustrate how to integrate AWS resources with physical devices. Walk away understanding how to get started with incident response and how you can use chaos engineering principles to create mechanisms that can improve your incident response processes.
TDR371-R | Workshop | Threat detection and response on AWS Join AWS experts for a hands-on threat detection and response workshop using Amazon GuardDuty, AWS Security Hub, and Amazon Detective. This workshop simulates security events for different types of resources and behaviors and illustrates both manual and automated responses with AWS Lambda. Dive in and learn how to improve your security posture by operationalizing threat detection and response on AWS.
TDR372-R | Workshop | Container threat detection with AWS security services Join AWS experts for a hands-on container security workshop using AWS threat detection and response services. This workshop simulates scenarios and security events while using Amazon EKS and demonstrates how to use different AWS security services to detect and respond to events and improve your security practices. Dive in and learn how to improve your security posture when running workloads on Amazon EKS.
Browse the full re:Inforce catalog to get details on additional sessions and content at the event, including gamified learning, leadership sessions, partner sessions, and labs.
If you want to learn the latest threat detection and incident response best practices and updates, join us in California by registering for re:Inforce 2023. We look forward to seeing you there!
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
About five years ago I announced that AWS Documentation is Now Open Source and on GitHub. After a prolonged period of experimentation we will archive most of the repos starting the week of June 5th, and will devote all of our resources to directly improving the AWS documentation and website.
The primary source for most of the AWS documentation is on internal systems that we had to manually sync with the GitHub repos. Despite the best efforts of our documentation team, keeping the public repos in sync with our internal ones has proven to be very difficult and time consuming, with several manual steps and some parallel editing. With 262 separate repos and thousands of feature launches every year, the overhead was very high and actually consumed precious time that could have been put to use in ways that more directly improved the quality of the documentation.
Our intent was to increase value to our customers through openness and collaboration, but we learned through customer feedback that this wasn’t necessarily the case. After carefully considering many options we decided to retire the repos and to invest all of our resources in making the content better.
Repos containing code samples, sample apps, CloudFormation templates, configuration files, and other supplementary resources will remain as-is since those repos are primary sources and get a high level of engagement.
To help us improvement the documentation, we’re also focusing more resources on your feedback:
We watch the thumbs-up and thumbs-down metrics on a weekly basis, and use the metrics as top-level pointers to areas of the documentation that could be improved. The incoming feedback creates tickets that are routed directly to the person or the team that is responsible for the page. I strongly encourage you to make frequent use of both feedback mechanisms.
At Amazon Web Services (AWS), we’re committed to providing our customers with continued assurance over the security, availability, confidentiality, and privacy of the AWS control environment.
We’re proud to deliver the Spring 2023 System and Organization Controls (SOC) 1, 2 and 3 reports, which cover October 1, 2022, to March 31, 2023, to support your confidence in AWS services. SOC reports are independent third-party examination reports that demonstrate how AWS achieves key compliance controls and objectives.
In the past, the Privacy SOC 2 report was issued separately from the other reports. However, starting with this Spring 2023 reporting cycle, the SOC 2 report is now consolidated and covers the Security, Availability, Confidentiality, and Privacy Trust Service Criteria.
The Spring 2023 SOC reports include four additional services in scope, for a total of 158 services. See the full list on our Services in Scope by Compliance Program page.
The following are the four additional services now in scope for the Spring 2023 SOC reports:
Five additional AWS Regions have been added to the scope, for a total of 29 Regions. The following are the five additional Regions now in scope for the Spring 2023 SOC reports:
Australia: Asia Pacific (Melbourne) (ap-southeast-4)
India: Asia Pacific (Hyderabad) (ap-south-2)
Spain: Europe (Spain) (eu-south-2)
Switzerland: Europe (Zurich) (eu-central-2)
United Arab Emirates: Middle East (UAE) (me-central-1)
AWS strives to bring services into the scope of its compliance programs to help you meet your architectural and regulatory needs. If there are additional AWS services you would like to see added to the scope of our SOC reports (or other compliance programs), reach out to your AWS representatives.
As always, we value your feedback and questions. Feel free to reach out to the team through the Contact Us page. If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security how-to-content, news, and feature announcements? Follow us on Twitter.
Cyber Essentials Plus is a UK Government-backed, industry-supported certification scheme intended to help organizations demonstrate organizational cyber security against common cyber attacks. An independent third-party auditor certified by the Information Assurance for Small and Medium Enterprises (IASME) completed the audit. The scope of our Cyber Essentials Plus certificate covers AWS Europe (London), AWS Europe (Ireland), and AWS Europe (Frankfurt) Regions.
The NHS DSPT is a self-assessment that organizations use to measure their performance against data security and information governance requirements. The UK Department of Health and Social Care sets these requirements.
When customers move to the AWS Cloud, AWS is responsible for protecting the global infrastructure that runs our services offered in the AWS Cloud. AWS customers are the data controllers for patient health and care data, and are responsible for anything they put in the cloud or connect to the cloud. For more information, see the AWS Shared Security Responsibility Model.
As always, we value your feedback and questions. Reach out to the AWS Compliance team through the Contact Us page. If you have feedback about this post, submit a comment in the Comments section below. To learn more about our other compliance and security programs, see AWS Compliance Programs.
Want more AWS Security news? Follow us on Twitter.
Join us on Wednesday, May 17, for AWS Serverless Innovation Day, a free full-day virtual event. You will learn about AWS Serverless technologies and event-driven architectures from customers, experts, and leaders.
AWS Serverless Innovation Day is an event to empower builders and technical decision-makers with different AWS Serverless technologies, including AWS Lambda, Amazon Elastic Container Service (Amazon ECS) with AWS Fargate, Amazon EventBridge, and AWS Step Functions. The talks of the day will cover three key topics: event-driven architectures, serverless containers, and serverless functions, and how they can be utilized to build and modernize applications. Application modernization is a priority for organizations this year, and serverless helps to increase the software delivery speed and reduce the total cost of ownership.
Eric Johnson and Jessica Deen will be the hosts for the event. Holly Mesrobian, VP of Serverless Compute at AWS, will deliver the welcome keynote and share AWS’s vision for Serverless. The day ends with closing remarks from James Beswick and Usman Khalid, Events and Workflows Director at AWS.
The event is split into three groups of talks: event-driven architecture, serverless containers, and Lambda-based applications. Each group kicks off with a fireside chat between AWS customers and an AWS leader. You can learn how organizations, such as Capital One, PostNL, Pentasoft, Delta Air Lines, and Smartsheets, are using AWS Serverless technologies to solve their most challenging problems and continue to innovate.
During the day, all the sessions include demos and use cases, where you can learn the best practices and how to build applications. If you cannot attend all day, here are some of my favorite sessions to watch:
Building with serverless workflows at scale – Ben Smith will show you how to unleash the power of AWS Step Functions.
Event design and event-first development – In this session, David Boyne will show you a robust approach to event design with Amazon EventBridge.
Best practices for AWS Lambda – You will learn from Julian Wood how to get the most out of your functions.
Optimizing for cost using Amazon ECS – Scott Coulton will show you how to reduce operational overhead from the control plane with Amazon ECS.
There is no up-front registration required to join the AWS Serverless Innovation Day, but if you want to be notified before the event starts, get in-depth news, articles, and event updates, and get a notification when the on-demand videos are available, you can register on the event page. The event will be streamed on Twitch, LinkedIn Live, YouTube, and Twitter.
Since Amazon Aurora launched in 2014, hundreds of thousands of customers have chosen Aurora to run their most demanding applications. Aurora provides unparalleled high performance and availability at global scale with full MySQL and PostgreSQL compatibility at up to one-tenth the cost of commercial databases.
Many customers benefit from the cost-effectiveness of Aurora’s current simple, pay-per-request pricing for input/output (I/O) usage, removing the need to provision I/Os in advance. Customers also benefit from additional cost-saving innovations such as Amazon Aurora Serverless v2 (ASv2), which provides seamless scaling in fine-grained increments based on the application’s demands. For workloads with spikes in demand, you can save up to 90 percent in costs vs. provisioning capacity for peak load with ASv2.
Today, we are announcing the general availability of Amazon Aurora I/O-Optimized, a new cluster configuration that offers improved price performance and predictable pricing for customers with I/O-intensive applications, such as e-commerce applications, payment processing systems, and more. Aurora I/O-Optimized offers improved performance, increasing throughput and reducing latency to support your most demanding workloads.
You can now confidently predict costs for your most I/O-intensive workloads, with up to 40 percent cost savings when your I/O spend exceeds 25 percent of your current Aurora database spend. If you are using Reserved Instances, you will see even greater cost savings.
Now you have the flexibility to choose between the existing configuration newly called Aurora Standard, which is the existing pay-per-request pricing model that is cost-effective for applications with low-to-moderate I/O usage or the new Aurora I/O-Optimized configuration for I/O-intensive applications.
Getting Started with Aurora I/O-Optimized You can create a new database cluster using the Aurora I/O-Optimized configuration or convert your existing database clusters with a few clicks in the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs.
For the Aurora MySQL-Compatible Edition and Aurora PostgreSQL-Compatible Edition, you can choose either the Aurora Standard or Aurora I/O-Optimized configuration.
Aurora I/O-Optimized configuration is available in the latest version of Aurora MySQL version 3.03.1 and higher, Aurora PostgreSQL v15.2 and higher, v14.7 and higher, and v13.10 and higher.
This configuration supports Intel-based Aurora database instance types such as t3, r5, and r6i, Graviton-based database instance types such as t4g, r7g, and x2g, Aurora Serverless v2, Aurora Global Database, on-demand Aurora database instances, and reserved instances.
R7g instances for Amazon Aurora are powered by the latest generation AWS Graviton3 processors, delivering up to 30 percent performance gains and up to 20 percent improved price performance for Aurora, as compared to R6g instances.
In your existing Aurora clusters, you can switch the storage configuration to Aurora I/O-Optimized once every 30 days or switch back to Aurora Standard at any time. You can change the cluster storage configuration only at the cluster level. The change applies to all instances in the cluster.
After changing the configuration, you don’t need to reboot the database instances within the cluster to take advantage of the price-performance benefits of Aurora I/O-Optimized.
Now Available Amazon Aurora I/O-Optimized configuration is now generally available for Amazon Aurora MySQL-Compatible Edition and Aurora PostgreSQL-Compatible Edition in most AWS Regions where Aurora is available, with China (Beijing), China (Ningxia), AWS GovCloud (US-East), and AWS GovCloud (US-West) Regions coming soon.
Aurora is billed differently for the two configurations: Aurora Standard or Aurora I/O-Optimized. The latter doesn’t charge for I/Os, charging a set price for compute and storage relative to the former. For I/O-intensive applications, its price/performance will be better, and you can save up to 40 percent on costs. To see pricing examples, visit the Aurora Pricing page.
This post is written by Rahul Popat (Senior Solutions Architect) and Aneel Murari (Senior Solutions Architect)
Today, AWS X-Ray is announcing support for SnapStart-enabled AWS Lambda functions. Lambda SnapStart is a performance optimization that significantly improves the cold startup times for your functions. Announced at AWS re:Invent 2022, this feature delivers up to 10 times faster function startup times for latency-sensitive Java applications at no extra cost, and with minimal or no code changes.
X-Ray is a distributed tracing system that provides an end-to-end view of how an application is performing. X-Ray collects data about requests that your application serves and provides tools you can use to gain insight into opportunities for optimizations. Now you can use X-Ray to gain insights into the performance improvements of your SnapStart-enabled Lambda function.
With today’s feature launch, by turning on X-Ray tracing for SnapStart-enabled Lambda functions, you see separate subsegments corresponding to the Restore and Invoke phases for your Lambda function’s execution.
How does Lambda SnapStart work?
With SnapStart, the function’s initialization is done ahead of time when you publish a function version. Lambda takes an encrypted snapshot of the initialized execution environment and persists the snapshot in a tiered cache for low latency access.
When the function is first invoked or scaled, Lambda restores the cached execution environment from the persisted snapshot instead of initializing anew. This results in reduced startup times.
X-Ray tracing before this feature launch
Using an example of a Hello World application written in Java, a Lambda function is configured with SnapStart and fronted by Amazon API Gateway:
Before today’s launch, X-Ray was not supported for SnapStart-enabled Lambda functions. So if you had enabled X-Ray tracing for API Gateway, the X-Ray trace for the sample application would look like:
The trace only shows the overall duration of the Lambda service call. You do not have insight into your function’s execution or the breakdown of different phases of Lambda function lifecycle.
Next, enable X-Ray for your Lambda function and see how you can view a breakdown of your function’s total execution duration.
Prerequisites for enabling X-Ray for SnapStart-enabled Lambda function
SnapStart is only supported for Lambda functions with Java 11 and newly launched Java 17 managed runtimes. You can only enable SnapStart for the published versions of your Lambda function. Once you’ve enabled SnapStart, Lambda publishes all subsequent versions with snapshots. You may also create a Lambda function alias, which points to the published version of your Lambda function.
Make sure that the Lambda function’s execution role has appropriate permissions to write to X-Ray.
Enabling AWS X-Ray for your Lambda function with SnapStart
This blog shows how you can achieve this via AWS Management Console and AWS SAM. For more information on enabling SnapStart and X-Ray using other methods, refer to AWS Lambda Developer Guide.
Enabling SnapStart and X-Ray via AWS Management Console
On the Configuration tab, choose Edit and change the SnapStart attribute value from None to PublishedVersions.
Choose Save.
To enable X-Ray via the AWS Management Console:
Navigate to your Lambda Function.
On the Configuration tab, scroll down to the Monitoring and operations tools card and choose Edit.
Under AWS X-Ray, enable Active tracing.
Choose Save
To publish a new version of Lambda function via the AWS Management Console:
Navigate to your Lambda Function.
On the Version tab, choose Publish new version.
Verify that PublishedVersions is shown below SnapStart.
Choose Publish.
To create an alias for a published version of your Lambda function via the AWS Management Console:
Navigate to your Lambda Function.
On the Aliases tab, choose Create alias.
Provide a Name for an alias and select a Version of your Lambda function to point the alias to.
Choose Save.
Enabling SnapStart and X-Ray via AWS SAM
To enable SnapStart and X-Ray for Lambda function via AWS SAM:
Enable Lambda function versions and create an alias by adding a AutoPublishAlias property in template.yaml file. AWS SAM automatically publishes a new version for each new deployment and automatically assigns the alias to the newly published version.
Resources:
  my-function:
    type: AWS::Serverless::Function
    Properties:
      […]
      AutoPublishAlias: live
Enable SnapStart on Lambda function by adding the SnapStart property in template.yaml file.
Enable X-Ray for Lambda function by adding the Tracing property in template.yaml file.
Resources:
  my-function:
    type: AWS::Serverless::Function
    Properties:
      […]
      Tracing: Active
You can find the complete AWS SAM template for the preceding example in this GitHub repository.
Using X-Ray to gain insights into SnapStart-enabled Lambda function’s performance
To demonstrate X-Ray integration for your Lambda function with SnapStart, you can build, deploy, and test the sample Hello World application using AWS SAM CLI. To do this, follow the instructions in the README file of the GitHub project.
The build and deployment output with AWS SAM looks like this:
Once your application is deployed to your AWS account, note that SnapStart and X-Ray tracing is enabled for your Lambda function. You should also see an alias `live` created against the published version of your Lambda function.
You should also have an API deployed via API Gateway, which is pointing to the `live` alias of your Lambda function as the backend integration.
Now, invoke your API via `curl` command or any other HTTP client. Make sure to replace the url with your own API’s url.
$ curl --location --request GET https://{rest-api-id}.execute-api.{region}.amazonaws.com/{stage}/hello
Navigate to Amazon CloudWatch and under the X-Ray service map, you see a visual representation of the trace data generated by your application.
Under Traces, you can see the individual traces, Response code, Response time, Duration, and other useful metrics.
Select a trace ID to see the breakdown of total Duration on your API call.
You can now see the complete trace for the Lambda function’s invocation with breakdown of time taken during each phase. You can see the Restore duration and actual Invocation duration separately.
Restore duration shown in the trace includes the time it takes for Lambda to restore a snapshot on the microVM, load the runtime (JVM), and run any afterRestore hooks if specified in your code. Note that, the process of restoring snapshots can include time spent on activities outside the microVM. This time is not reported in the Restore sub-segment, but is part of the AWS::Lambda segment in X-Ray traces.
This helps you better understand the latency of your Lambda function’s execution, and enables you to identify and troubleshoot the performance issues and errors.
Conclusion
This blog post shows how you can enable AWS X-Ray for your Lambda function enabled with SnapStart, and measure the end-to-end performance of such functions using X-Ray console. You can now see a complete breakdown of your Lambda function’s execution time. This includes Restore duration along with the Invocation duration, which can help you to understand your application’s startup times (cold starts), diagnose slowdowns, or troubleshoot any errors and timeouts.
AWS is pleased to announce the publication of a checklist to help customers align with the requirements of the European Union’s electronic identification, authentication, and trust services (eIDAS) regulation regarding the use of electronic identities and trust services. The eIDAS regulation covers electronic identification and trust services for electronic transactions in the European single market.
This checklist is intended as a reference and supporting document to help institutions align with the requirements of eIDAS and the European Telecommunications Standards Institute (ETSI). Where applicable, under the AWS Shared Responsibility Model, this checklist provides supporting details and references in relation to AWS to assist institutions when adopting eIDAS and ETSI for their workloads on AWS services.
For the controls that AWS is fully or partially responsible for, the checklist compares the eIDAS and ETSI requirements to the following:
This checklist is valid until the current eIDAS EU regulation 910/2014, published July 23rd, 2014, ceases to be in force. The checklist is available upon request.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Today we are launching I4g instances powered by AWS Graviton2 processors that deliver up to 15% better compute performance than our other storage-optimized instances.
With up to 64 vCPUs, 512 GiB of memory, and 15 TB of NVMe storage, one of the six instance sizes is bound to be a great fit for your storage-intensive workloads: relational and non-relational databases, search engines, file systems, in-memory analytics, batch processing, streaming, and so forth. These workloads are generally very sensitive to I/O latency, and require plenty of random read/write IOPS along with high CPU performance.
Available Now I4g instances are available today in the US East (Ohio, N. Virginia), US West (Oregon), and Europe (Ireland) AWS Regions in On-Demand, Spot, Reserved Instance, and Savings Plan form.
A full conference pass is $1,099. Register today with the code secure150off to receive a limited time $150 discount, while supplies last.
AWS re:Inforce 2023 is fast approaching, and this post can help you plan your agenda with a look at the sessions in the identity and access management track. AWS re:Inforce is a learning conference where you can learn more about cloud security, compliance, identity, and privacy. You have access to hundreds of technical and non-technical sessions, an AWS Partner expo featuring security partners with AWS Security Competencies, and keynote and leadership sessions featuring AWS Security leadership. AWS re:Inforce 2023 will take place in-person in Anaheim, California, on June 13 and 14. re:Inforce 2023 features content in the following six areas:
The identity and access management track will share recommended practices and learnings for identity management and governance in AWS environments. You will hear from other AWS customers about how they are building customer identity and access management (CIAM) patterns for great customer experiences and new approaches for managing standard, elevated, and privileged workforce access. You will also hear from AWS leaders about accelerating the journey to least privilege with access insights and the role of identity within a Zero Trust architecture.
This post highlights some of the identity and access management sessions that you can sign up for, including breakout sessions, chalk talks, code talks, lightning talks, builders’ sessions, and workshops. For the full catalog, see the AWS re:Inforce catalog preview.
Breakout sessions
Lecture-style presentations that cover topics at all levels and delivered by AWS experts, builders, customers, and partners. Breakout sessions typically include 10–15 minutes of Q&A at the end.
IAM201: A first-principles approach: AWS Identity and Access Management (IAM) Learning how to build effectively and securely on AWS starts with a strong working knowledge of AWS Identity and Access Management (IAM). In this session aimed at engineers who build on AWS, explore a no-jargon, first-principles approach to IAM. Learn the fundamental concepts of IAM authentication and authorization policies as well as concrete techniques that you can immediately apply to the workloads you run on AWS.
IAM301: Establishing a data perimeter on AWS, featuring USAA In this session, dive deep into the data perimeter controls that help you manage your trusted identities and their access to trusted resources from expected networks. USAA shares how they use automation to embed security and AWS Identity and Access Management (IAM) baselines to empower a self-service mindset. Learn how they use data perimeters to support decentralization without compromising on security. Also, discover how USAA uses a threat-based approach to prioritize implementation of specific data perimeters.
IAM302: Create enterprise-wide preventive guardrails, featuring Inter & Co. In this session, learn how to establish permissions guardrails within your multi-account environment with AWS Organizations and service control policies (SCPs). Explore how effective use of SCPs can help your builders innovate on AWS while maintaining a high bar on security. Learn about the strategies to incorporate SCPs at different levels within your organization. In addition, Inter & Co. share their strategies for implementing enterprise-wide guardrails at scale within their multi-account environments. Discover how they use code repositories and CI/CD pipelines to manage approvals and deployments of SCPs.
IAM303: Balance least privilege & agile development, feat. Fidelity & Merck Finding a proper balance between securing multiple AWS accounts and enabling agile development to accelerate business innovation has been key to the cloud adoption journey for AWS customers. In this session, learn how Fidelity and Merck empowered their business stakeholders to quickly develop solutions while still conforming to security standards and operating within the guardrails at scale.
IAM304: Migrating to Amazon Cognito, featuring approaches from Fandango Digital transformation of customer-facing applications often involves changes to identity and access management to help improve security and user experience. This process can benefit from fast-growing technologies and open standards and may involve migration to a modern customer identity and access management solution, such as Amazon Cognito, that offers the security and scale your business requires. There are several ways to approach migrating users to Amazon Cognito. In this session, learn about options and best practices, as well as lessons learned from Fandango’s migration to Amazon Cognito.
IAM305: Scaling access with AWS IAM Identity Center, feat. Allegiant Airlines In this session, learn how to scale assignment of permission sets to users and groups by automating federated role-based access to any AWS accounts in your organization. As a highlight of this session, hear Allegiant Airlines’ success story of how this automation has benefited Allegiant by centralizing management of federated access for their organization of more than 5,000 employees. Additionally, explore how to build this automation in your environment using infrastructure as code tools like Terraform and AWS CloudFormation using a CI/CD pipeline.
IAM306: Managing hybrid workloads with IAM Roles Anywhere, featuring Hertz A key element of using AWS Identity and Access Management (IAM) Roles Anywhere is managing how identities are assigned to your workloads. In this session, learn how you can define and manage identities for your workloads, how to use those identities to control access to an AWS resource via attribute-based access control (ABAC), and how to monitor and audit activities performed by those identities. Discover key concepts, best practices, and troubleshooting tips. Hertz describes how they used IAM Roles Anywhere to secure access to AWS services from Salesforce and how it has improved their overall security posture.
IAM307: Steps towards a Zero Trust architecture on AWS Modern workplaces have evolved beyond traditional network boundaries as they have expanded to hybrid and multi-cloud environments. Identity has taken center stage for information security teams. The need for fine-grained, identity-based authorization, flexible identity-aware networks, and the removal of unneeded pathways to data has accelerated the adoption of Zero Trust principles and architecture. In this session, learn about different architecture patterns and security mechanisms available from AWS that you can apply to secure standard, sensitive, and privileged access to your critical data and workloads.
Builders’ sessions
Small-group sessions led by an AWS expert who guides you as you build the service or product on your own laptop. Use your laptop to experiment and build along with the AWS expert.
IAM351: Sharing resources across accounts with least-privilege permissions Are you looking to manage your resource access control permissions? Learn how you can author customer managed permissions to provide least-privilege access to your resources shared using AWS Resource Access Manager (AWS RAM). Explore how to use customer managed permissions with use cases ranging from managing incident response with AWS Systems Manager Incident Manager to enhancing your IP security posture with Amazon VPC IP Address Manager.
IAM352: Cedar policy language in action Cedar is a language for defining permissions as policies that describe who should have access to what. Amazon Verified Permissions and AWS Verified Access use Cedar to define fine-grained permissions for applications and end users. In this builders’ session, come learn by building Cedar policies for access control.
IAM355: Using passwordless authentication with Amazon Cognito and WebAuthn In recent years, passwordless authentication has been on the rise. The FIDO Alliance, a first-mover for enabling passwordless in 2009, is an open industry association whose stated mission is to develop and promote authentication standards that “help reduce the world’s over-reliance on passwords.” This builders’ session allows participants to learn about and follow the steps to implement a passwordless authentication experience on a web or mobile application using Amazon Cognito.
IAM356: AWS Identity and Access Management (IAM) policies troubleshooting In this builders’ session, walk through practical examples that can help you build, test, and troubleshoot AWS Identity and Access Management (IAM) policies. Utilize a workflow that can help you create fine-grained access policies with the help of the IAM API, the AWS Management Console, and AWS CloudTrail. Also review key concepts of IAM policy evaluation logic.
Chalk talks
Highly interactive sessions with a small audience. Experts lead you through problems and solutions on a digital whiteboard as the discussion unfolds.
IAM231: Lessons learned from AWS IAM Identity Center migrations In this chalk talk, discover best practices and tips to migrate your workforce users’ access from IAM users to AWS IAM Identity Center (successor to AWS Single Sign-On). Learn how to create preventive guardrails, gain visibility into the usage of IAM users across an organization, and apply authentication solutions for common use cases.
IAM331: Leaving IAM access keys behind: A modern path forward Static credentials have been used for a long time to secure multiple types of access, including access keys for AWS Identity and Access Management (IAM) users, command line tools, secure shell access, application API keys, and pre-shared keys for VPN access. However, best practice recommends replacing static credentials with short-term credentials. In this chalk talk, learn how to identify static access keys in your environment, quantify the risk, and then apply multiple available methods to replace them with short-term credentials. The talk also covers prescriptive guidance and best practice advice for improving your overall management of IAM access keys.
IAM332: Practical identity and access management: The basics of IAM on AWS Learn from prescriptive guidance on how to build an Identity and Access Management strategy on AWS. We provide guidance on human access versus machine access using services like IAM Identity Center. You will also learn about the different IAM policy types, where each policy type is useful, and how you should incorporate each policy type in your AWS environment. This session will walk you through what you need to know to build an effective identity and access management baseline.
IAM431: A tour of the world of IAM policy evaluation This session takes you beyond the basics of IAM policy evaluation and focuses on how policy evaluation works with advanced AWS features. Hear about how policies are evaluated alongside AWS Key Management Service (AWS KMS) key grants, Amazon Simple Storage Service (Amazon S3) and Amazon Elastic File System (Amazon EFS) access points, Amazon VPC Lattice, and more. You’ll leave this session with prescriptive guidance on what to do and what to avoid when designing authorization schemes.
Code talks
Engaging, code-focused sessions with a small audience. AWS experts lead an interactive discussion featuring live coding and/or code samples as they explain the “why” behind AWS solutions.
IAM341: Cedar: Fast, safe, and fine-grained access for your applications Cedar is a new policy language that helps you write fine-grained permissions in your applications. With Cedar, you can customize authorization and you can define and enforce who can access what. This code talk explains the design of Cedar, how it was built to a high standard of assurance, and its benefits. Learn what makes Cedar ergonomic, fast, and analyzable: simple syntax for expressing common authorization use cases, policy structure that allows for scalable real-time evaluation, and comprehensive auditing based on automated reasoning. Also find out how Cedar’s implementation was made safer through formal verification and differential testing.
IAM441: Enable new Amazon Cognito use cases with OAuth2.0 flows Delegated authorization without user interaction on a consumer device and reinforced passwordless authentication for higher identity assurance are advanced authentication flows achievable with Amazon Cognito. In this code talk, you can discover new OAuth2.0 flow diagrams, code snippets, and long and short demos that offer different approaches to these authentication use cases. Gain confidence using AWS Lambda triggers with Amazon Cognito, native APIs, and OAuth2.0 endpoints to help ensure greater success in customer identity and access management strategy.
Lightning talks
Short and focused theater presentations that are dedicated to either a specific customer story, service demo, or partner offering (sponsored).
IAM221: Accelerate your business with AWS Directory Service In this lightning talk, explore AWS Directory Service for Microsoft Active Directory and discover a number of use cases that provide flexibility, empower agile application development, and integrate securely with other identity stores. Join the talk to discover how you can take advantage of this managed service and focus on what really matters to your customers.
IAM321: Move toward least privilege with IAM Access Analyzer AWS Identity and Access Management (IAM) Access Analyzer provides tools that simplify permissions management by making it easy for organizations to set, verify, and refine permissions. In this lightning talk, dive into how you can detect resources shared with an external entity across one or multiple AWS accounts with IAM Access Analyzer. Find out how you can activate and use this feature and how it integrates with AWS Security Hub.
Workshops
Interactive learning sessions where you work in small teams to solve problems using AWS Cloud security services. Come prepared with your laptop and a willingness to learn!
IAM371: Building a Customer Identity and Access Management (CIAM) solution How do your customers access your application? Get a head start on customer identity and access management (CIAM) by using Amazon Cognito. Join this workshop to learn how to build CIAM solutions on AWS using Amazon Cognito, Amazon Verified Permissions, and several other AWS services. Start from the basic building blocks of CIAM and build up to advanced user identity and access management use cases in customer-facing applications.
IAM372: Consuming AWS Resources from everywhere with IAM Roles Anywhere If your workload already lives on AWS, then there is a high chance that some temporary AWS credentials have been securely distributed to perform needed tasks. But what happens when your workload is on premises? In this workshop, learn how to use AWS Identity and Access Management (IAM) Roles Anywhere. Start from the basics and create the necessary steps to learn how to use your applications outside of AWS in a safe way using IAM Roles Anywhere in practice.
IAM373: Building a data perimeter to allow access to authorized users In this workshop, learn how to create a data perimeter by building controls that allow access to data only from expected network locations and by trusted identities. The workshop consists of five modules, each designed to illustrate a different AWS Identity and Access Management (IAM) principle or network control. Learn where and how to implement the appropriate controls based on different risk scenarios.
If these sessions look interesting to you, join us in Anaheim by registering for AWS re:Inforce 2023. We look forward to seeing you there!
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
At the end of this week, I’m flying to Seattle to take part in the AWS Serverless Innovation Day. Along with many customers and colleagues from AWS, we are going to be live on May 17 at a virtual free event. During the AWS Serverless Innovation Day we will share best practices related to building event-driven applications and using serverless functions and containers. Get a calendar reminder and check the full agenda at the event site.
Last Week’s Launches Here are some launches that got my attention during the previous week.
New Local Zones in Auckland – AWS Local Zones allow you to deliver applications that require single-digit millisecond latency or local data processing. Starting last week, AWS Local Zones is available in Auckland, New Zealand.
AWS AppSync– Now AWS AppSync GraphQL APIs support Private API. With Private APIs, you can now create GraphQL APIs that can only be accessed from your Amazon Virtual Private Cloud (Amazon VPC).
Other AWS News Some other updates and news that you may have missed:
Responsible AI in the Generative Era – Amazon Science published a very interesting blog post this week about the special challenges raised by building a responsible generative AI and the different things builders of applications can do in order to solve these challenges.
Patterns for Building an API to Upload Files to AmazonS3 – Amazon S3 is one of the most used services by our customers, and applications often require a way for users to upload files. In this article, Thomas Moore shows different ways to do this in a secure way.
The Official AWS Podcast– Listen each week for updates on the latest AWS news and deep dives into exciting use cases. There are also official AWS podcasts in your local languages. Check out the ones in French, German, Italian, and Spanish.
AWS Open-Source News and Updates – This is a newsletter curated by my colleague Ricardo to bring you the latest open-source projects, posts, events, and more.
Upcoming AWS Events Check your calendars and sign up for these AWS events:
AWS Serverless Innovation Day – Join us on May 17 for a virtual and free event about AWS Serverless. We will have talks and fireside chats with customers related to AWS Lambda, Amazon ECS with Fargate, AWS Step Functions, and Amazon EventBridge.
AWS re:Inforce 2023 – You can now register for AWS re:Inforce, happening in Anaheim, California, on June 13–14.
AWS Community Day – Join a community-led conference run by AWS user group leaders in your region: Warsaw (June 1), Chicago (June 15), Manila (June 29–30), and Munich (September 14).
AWS User Group Peru Conference – The local AWS User Group announced a one-day cloud event in Spanish and English in Lima on September 23. Seb, Jeff, and I will be attending the event from the AWS News blog team. Register today!
That’s all for this week. Check back next Monday for another Week in Review!
Users often need to extract important components like bucket and key from stored S3 URIs to use in S3Client operations. The new parsing APIs allow users to conveniently do so, bypassing the need for manual parsing or storing the components separately.
Getting Started
To begin, first add the dependency for S3 to your project.
To parse your S3 URI, call parseUri() from S3Utilities, passing in the URI. This will return a parsed S3Uri object. If you have a String of the URI, you’ll need to convert it into an URI object first.
String url = "https://s3.us-west-1.amazonaws.com/myBucket/resources/doc.txt?versionId=abc123&partNumber=77&partNumber=88";
URI uri = URI.create(url);
S3Uri s3Uri = s3Utilities.parseUri(uri);
With the S3Uri, you can call the appropriate getter methods to retrieve the bucket, key, region, style, and query parameters. If the bucket, key, or region is not specified in the URI, an empty Optional will be returned. If query parameters are not specified in the URI, an empty map will be returned. If the field is encoded in the URI, it will be returned decoded.
There are several APIs for retrieving the query parameters. You can return a Map<String, List<String>> of the query parameters. Alternatively, you can specify a query parameter to return the first value for the given query, or return the list of values for the given query.
If you work with object keys or query parameters with reserved or unsafe characters, they must be URL-encoded, e.g., replace whitespace " " with "%20".
In this post, I discussed parsing S3 URIs in the AWS SDK for Java 2.x and provided code examples for retrieving the bucket, key, region, style, and query parameters. To learn more about how to set up and begin using the feature, visit our Developer Guide. If you are curious about how it is implemented, check out the source code on GitHub. As always, the AWS SDK for Java team welcomes bug reports, feature requests, and pull requests on the aws-sdk-java-v2 GitHub repository.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.



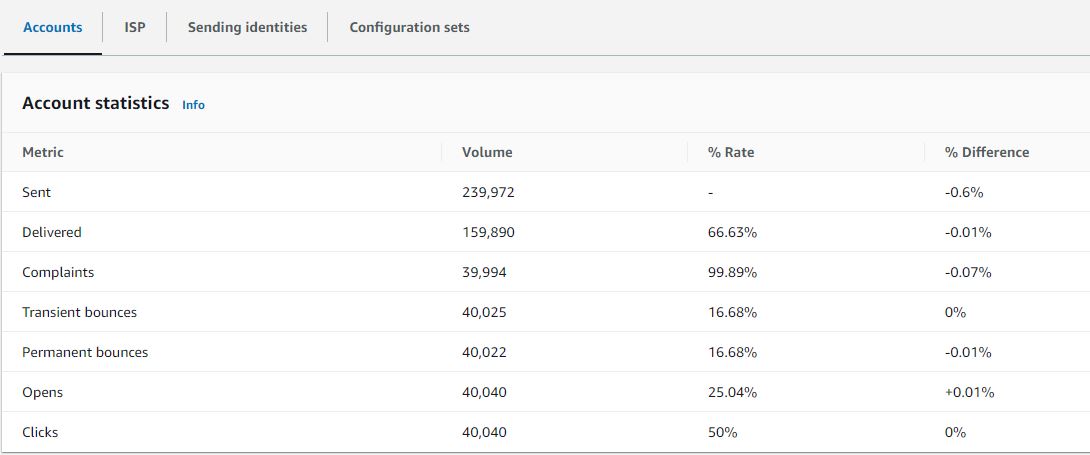
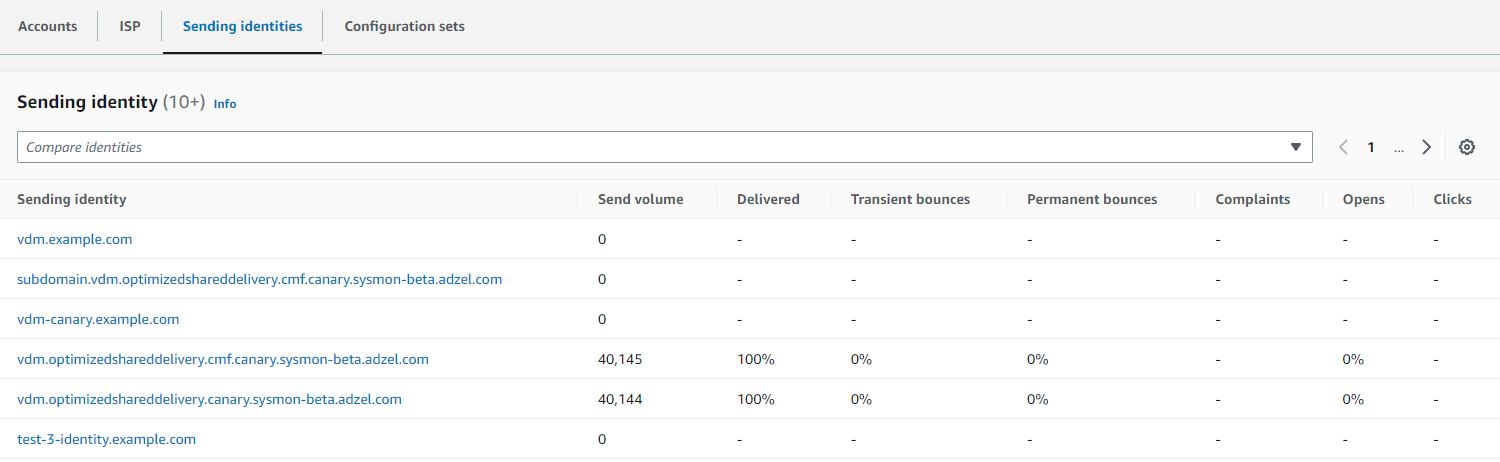

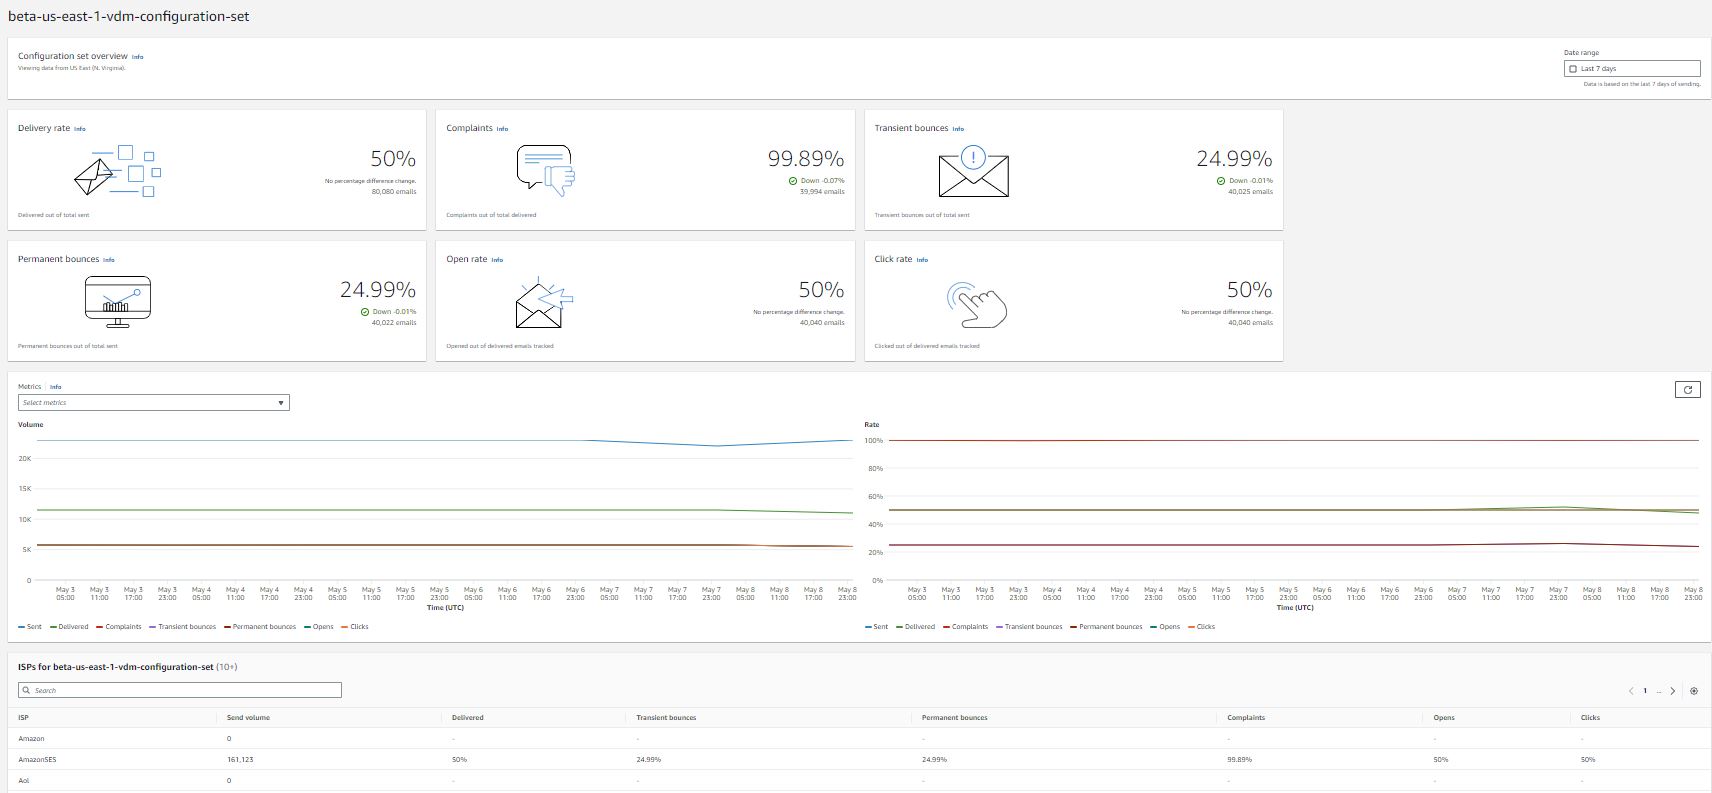
 If you have previously leased several standard dedicated IP addresses to use with Amazon SES, you would have created groups of those addresses, called dedicated IP pools. Grouping dedicated IPs together in a pool makes them easier to manage. A common scenario is to create one pool for sending marketing communications, and another for sending transactional emails. Your sender reputation for transactional emails is then isolated from that of your marketing emails. In this scenario, if a marketing campaign generates a large number of complaints, the delivery of your transactional emails is not impacted. If you already have dedicated IPs (standard) pools you can now convert these pools to managed IP pools in one click. Converting from a dedicated IP (standard) pool to a dedicated IP (managed) pool automatically transfers all of your standard IPs over to managed. So, you keep the same set of IPs, but you no longer have to worry about monitoring and managing them. You will no longer be charged per IP that you lease, but rather by the volume of emails that you send. For more information on pricing see the


 During the preview, we had lots of interest and great feedback from customers. Today, Amazon SageMaker geospatial capabilities are generally available with new security updates and additional sample use cases.