Tag Archives: Uncategorized

I’m Spending the Year at the Munk School

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/im-spending-the-year-at-the-munk-school.html

This academic year, I am taking a sabbatical from the Kennedy School and Harvard University. (It’s not a real sabbatical—I’m just an adjunct—but it’s the same idea.) I will be spending the Fall 2025 and Spring 2026 semesters at the Munk School at the University of Toronto.

I will be organizing a reading group on AI security in the fall. I will be teaching my cybersecurity policy class in the Spring. I will be working with Citizen Lab, the Law School, and the Schwartz Reisman Institute. And I will be enjoying all the multicultural offerings of Toronto.

It’s all pretty exciting.

AI Agents Need Data Integrity

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/ai-agents-need-data-integrity.html

Think of the Web as a digital territory with its own social contract. In 2014, Tim Berners-Lee called for a “Magna Carta for the Web” to restore the balance of power between individuals and institutions. This mirrors the original charter’s purpose: ensuring that those who occupy a territory have a meaningful stake in its governance.

Web 3.0—the distributed, decentralized Web of tomorrow—is finally poised to change the Internet’s dynamic by returning ownership to data creators. This will change many things about what’s often described as the “CIA triad” of digital security: confidentiality, integrity, and availability. Of those three features, data integrity will become of paramount importance.

When we have agency in digital spaces, we naturally maintain their integrity—protecting them from deterioration and shaping them with intention. But in territories controlled by distant platforms, where we’re merely temporary visitors, that connection frays. A disconnect emerges between those who benefit from data and those who bear the consequences of compromised integrity. Like homeowners who care deeply about maintaining the property they own, users in the Web 3.0 paradigm will become stewards of their personal digital spaces.

This will be critical in a world where AI agents don’t just answer our questions but act on our behalf. These agents may execute financial transactions, coordinate complex workflows, and autonomously operate critical infrastructure, making decisions that ripple through entire industries. As digital agents become more autonomous and interconnected, the question is no longer whether we will trust AI but what that trust is built upon. In the new age we’re entering, the foundation isn’t intelligence or efficiency—it’s integrity.

What Is Data Integrity?

In information systems, integrity is the guarantee that data will not be modified without authorization, and that all transformations are verifiable throughout the data’s life cycle. While availability ensures that systems are running and confidentiality prevents unauthorized access, integrity focuses on whether information is accurate, unaltered, and consistent across systems and over time.

It’s a new idea. The undo button, which prevents accidental data loss, is an integrity feature. So is the reboot process, which returns a computer to a known good state. Checksums are an integrity feature; so are verifications of network transmission. Without integrity, security measures can backfire. Encrypting corrupted data just locks in errors. Systems that score high marks for availability but spread misinformation just become amplifiers of risk.

All IT systems require some form of data integrity, but the need for it is especially pronounced in two areas today. First: Internet of Things devices interact directly with the physical world, so corrupted input or output can result in real-world harm. Second: AI systems are only as good as the integrity of the data they’re trained on, and the integrity of their decision-making processes. If that foundation is shaky, the results will be too.

Integrity manifests in four key areas. The first, input integrity, concerns the quality and authenticity of data entering a system. When this fails, consequences can be severe. In 2021, Facebook’s global outage was triggered by a single mistaken command—an input error missed by automated systems. Protecting input integrity requires robust authentication of data sources, cryptographic signing of sensor data, and diversity in input channels for cross-validation.

The second issue is processing integrity, which ensures that systems transform inputs into outputs correctly. In 2003, the U.S.-Canada blackout affected 55 million people when a control-room process failed to refresh properly, resulting in damages exceeding US $6 billion. Safeguarding processing integrity means formally verifying algorithms, cryptographically protecting models, and monitoring systems for anomalous behavior.

Storage integrity covers the correctness of information as it’s stored and communicated. In 2023, the Federal Aviation Administration was forced to halt all U.S. departing flights because of a corrupted database file. Addressing this risk requires cryptographic approaches that make any modification computationally infeasible without detection, distributed storage systems to prevent single points of failure, and rigorous backup procedures.

Finally, contextual integrity addresses the appropriate flow of information according to the norms of its larger context. It’s not enough for data to be accurate; it must also be used in ways that respect expectations and boundaries. For example, if a smart speaker listens in on casual family conversations and uses the data to build advertising profiles, that action would violate the expected boundaries of data collection. Preserving contextual integrity requires clear data-governance policies, principles that limit the use of data to its intended purposes, and mechanisms for enforcing information-flow constraints.

As AI systems increasingly make critical decisions with reduced human oversight, all these dimensions of integrity become critical.

The Need for Integrity in Web 3.0

As the digital landscape has shifted from Web 1.0 to Web 2.0 and now evolves toward Web 3.0, we’ve seen each era bring a different emphasis in the CIA triad of confidentiality, integrity, and availability.

Returning to our home metaphor: When simply having shelter is what matters most, availability takes priority—the house must exist and be functional. Once that foundation is secure, confidentiality becomes important—you need locks on your doors to keep others out. Only after these basics are established do you begin to consider integrity, to ensure that what’s inside the house remains trustworthy, unaltered, and consistent over time.

Web 1.0 of the 1990s prioritized making information available. Organizations digitized their content, putting it out there for anyone to access. In Web 2.0, the Web of today, platforms for e-commerce, social media, and cloud computing prioritize confidentiality, as personal data has become the Internet’s currency.

Somehow, integrity was largely lost along the way. In our current Web architecture, where control is centralized and removed from individual users, the concern for integrity has diminished. The massive social media platforms have created environments where no one feels responsible for the truthfulness or quality of what circulates.

Web 3.0 is poised to change this dynamic by returning ownership to the data owners. This is not speculative; it’s already emerging. For example, ActivityPub, the protocol behind decentralized social networks like Mastodon, combines content sharing with built-in attribution. Tim Berners-Lee’s Solid protocol restructures the Web around personal data pods with granular access controls.

These technologies prioritize integrity through cryptographic verification that proves authorship, decentralized architectures that eliminate vulnerable central authorities, machine-readable semantics that make meaning explicit—structured data formats that allow computers to understand participants and actions, such as “Alice performed surgery on Bob”—and transparent governance where rules are visible to all. As AI systems become more autonomous, communicating directly with one another via standardized protocols, these integrity controls will be essential for maintaining trust.

Why Data Integrity Matters in AI

For AI systems, integrity is crucial in four domains. The first is decision quality. With AI increasingly contributing to decision-making in health care, justice, and finance, the integrity of both data and models’ actions directly impact human welfare. Accountability is the second domain. Understanding the causes of failures requires reliable logging, audit trails, and system records.

The third domain is the security relationships between components. Many authentication systems rely on the integrity of identity information and cryptographic keys. If these elements are compromised, malicious agents could impersonate trusted systems, potentially creating cascading failures as AI agents interact and make decisions based on corrupted credentials.

Finally, integrity matters in our public definitions of safety. Governments worldwide are introducing rules for AI that focus on data accuracy, transparent algorithms, and verifiable claims about system behavior. Integrity provides the basis for meeting these legal obligations.

The importance of integrity only grows as AI systems are entrusted with more critical applications and operate with less human oversight. While people can sometimes detect integrity lapses, autonomous systems may not only miss warning signs—they may exponentially increase the severity of breaches. Without assurances of integrity, organizations will not trust AI systems for important tasks, and we won’t realize the full potential of AI.

How to Build AI Systems With Integrity

Imagine an AI system as a home we’re building together. The integrity of this home doesn’t rest on a single security feature but on the thoughtful integration of many elements: solid foundations, well-constructed walls, clear pathways between rooms, and shared agreements about how spaces will be used.

We begin by laying the cornerstone: cryptographic verification. Digital signatures ensure that data lineage is traceable, much like a title deed proves ownership. Decentralized identifiers act as digital passports, allowing components to prove identity independently. When the front door of our AI home recognizes visitors through their own keys rather than through a vulnerable central doorman, we create resilience in the architecture of trust.

Formal verification methods enable us to mathematically prove the structural integrity of critical components, ensuring that systems can withstand pressures placed upon them—especially in high-stakes domains where lives may depend on an AI’s decision.

Just as a well-designed home creates separate spaces, trustworthy AI systems are built with thoughtful compartmentalization. We don’t rely on a single barrier but rather layer them to limit how problems in one area might affect others. Just as a kitchen fire is contained by fire doors and independent smoke alarms, training data is separated from the AI’s inferences and output to limit the impact of any single failure or breach.

Throughout this AI home, we build transparency into the design: The equivalent of large windows that allow light into every corner is clear pathways from input to output. We install monitoring systems that continuously check for weaknesses, alerting us before small issues become catastrophic failures.

But a home isn’t just a physical structure, it’s also the agreements we make about how to live within it. Our governance frameworks act as these shared understandings. Before welcoming new residents, we provide them with certification standards. Just as landlords conduct credit checks, we conduct integrity assessments to evaluate newcomers. And we strive to be good neighbors, aligning our community agreements with broader societal expectations. Perhaps most important, we recognize that our AI home will shelter diverse individuals with varying needs. Our governance structures must reflect this diversity, bringing many stakeholders to the table. A truly trustworthy system cannot be designed only for its builders but must serve anyone authorized to eventually call it home.

That’s how we’ll create AI systems worthy of trust: not by blindly believing in their perfection but because we’ve intentionally designed them with integrity controls at every level.

A Challenge of Language

Unlike other properties of security, like “available” or “private,” we don’t have a common adjective form for “integrity.” This makes it hard to talk about it. It turns out that there is a word in English: “integrous.” The Oxford English Dictionary recorded the word used in the mid-1600s but now declares it obsolete.

We believe that the word needs to be revived. We need the ability to describe a system with integrity. We must be able to talk about integrous systems design.

The Road Ahead

Ensuring integrity in AI presents formidable challenges. As models grow larger and more complex, maintaining integrity without sacrificing performance becomes difficult. Integrity controls often require computational resources that can slow systems down—particularly challenging for real-time applications. Another concern is that emerging technologies like quantum computing threaten current cryptographic protections. Additionally, the distributed nature of modern AI—which relies on vast ecosystems of libraries, frameworks, and services—presents a large attack surface.

Beyond technology, integrity depends heavily on social factors. Companies often prioritize speed to market over robust integrity controls. Development teams may lack specialized knowledge for implementing these controls, and may find it particularly difficult to integrate them into legacy systems. And while some governments have begun establishing regulations for aspects of AI, we need worldwide alignment on governance for AI integrity.

Addressing these challenges requires sustained research into verifying and enforcing integrity, as well as recovering from breaches. Priority areas include fault-tolerant algorithms for distributed learning, verifiable computation on encrypted data, techniques that maintain integrity despite adversarial attacks, and standardized metrics for certification. We also need interfaces that clearly communicate integrity status to human overseers.

As AI systems become more powerful and pervasive, the stakes for integrity have never been higher. We are entering an era where machine-to-machine interactions and autonomous agents will operate with reduced human oversight and make decisions with profound impacts.

The good news is that the tools for building systems with integrity already exist. What’s needed is a shift in mind-set: from treating integrity as an afterthought to accepting that it’s the core organizing principle of AI security.

The next era of technology will be defined not by what AI can do, but by whether we can trust it to know or especially to do what’s right. Integrity—in all its dimensions—will determine the answer.

Sidebar: Examples of Integrity Failures

Ariane 5 Rocket (1996)
Processing integrity failure
A 64-bit velocity calculation was converted to a 16-bit output, causing an error called overflow. The corrupted data triggered catastrophic course corrections that forced the US $370 million rocket to self-destruct.

NASA Mars Climate Orbiter (1999)
Processing integrity failure
Lockheed Martin’s software calculated thrust in pound-seconds, while NASA’s navigation software expected newton-seconds. The failure caused the $328 million spacecraft to burn up in the Mars atmosphere.

Microsoft’s Tay Chatbot (2016)
Processing integrity failure
Released on Twitter, Microsoft‘s AI chatbot was vulnerable to a “repeat after me” command, which meant it would echo any offensive content fed to it.

Boeing 737 MAX (2018)
Input integrity failure
Faulty sensor data caused an automated flight-control system to repeatedly push the airplane’s nose down, leading to a fatal crash.

SolarWinds Supply-Chain Attack (2020)
Storage integrity failure
Russian hackers compromised the process that SolarWinds used to package its software, injecting malicious code that was distributed to 18,000 customers, including nine federal agencies. The hack remained undetected for 14 months.

ChatGPT Data Leak (2023)
Storage integrity failure
A bug in OpenAI’s ChatGPT mixed different users’ conversation histories. Users suddenly had other people’s chats appear in their interfaces with no way to prove the conversations weren’t theirs.

Midjourney Bias (2023)
Contextual integrity failure
Users discovered that the AI image generator often produced biased images of people, such as showing white men as CEOs regardless of the prompt. The AI tool didn’t accurately reflect the context requested by the users.

Prompt Injection Attacks (2023–)
Input integrity failure
Attackers embedded hidden prompts in emails, documents, and websites that hijacked AI assistants, causing them to treat malicious instructions as legitimate commands.

CrowdStrike  Outage (2024)
Processing integrity failure
A faulty software update from CrowdStrike caused 8.5 million Windows computers worldwide to crash—grounding flights, shutting down hospitals, and disrupting banks. The update, which contained a software logic error, hadn’t gone through full testing protocols.

Voice-Clone Scams (2024)
Input and processing integrity failure
Scammers used AI-powered voice-cloning tools to mimic the voices of victims’ family members, tricking people into sending money. These scams succeeded because neither phone systems nor victims identified the AI-generated voice as fake.

This essay was written with Davi Ottenheimer, and originally appeared in IEEE Spectrum.

Jim Sanborn Is Auctioning Off the Solution to Part Four of the Kryptos Sculpture

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/jim-sanborn-is-auctioning-off-the-solution-to-part-four-of-the-kryptos-sculpture.html

Well, this is interesting:

The auction, which will include other items related to cryptology, will be held Nov. 20. RR Auction, the company arranging the sale, estimates a winning bid between $300,000 and $500,000.

Along with the original handwritten plain text of K4 and other papers related to the coding, Mr. Sanborn will also be providing a 12-by-18-inch copper plate that has three lines of alphabetic characters cut through with a jigsaw, which he calls “my proof-of-concept piece” and which he kept on a table for inspiration during the two years he and helpers hand-cut the letters for the project. The process was grueling, exacting and nerve wracking. “You could not make any mistake with 1,800 letters,” he said. “It could not be repaired.”

Mr. Sanborn’s ideal winning bidder is someone who will hold on to that secret. He also hopes that person is willing to take over the system of verifying possible solutions and reviewing those unending emails, possibly through an automated system.

Here’s the auction listing.

A Complete Guide to Resource Sharing for AWS End User Messaging

Post Syndicated from Brett Ezell original https://aws.amazon.com/blogs/messaging-and-targeting/a-complete-guide-to-resource-sharing-for-aws-end-user-messaging/

Introduction

Do you need to send SMS across multiple AWS accounts? Or have you ever wanted to use the same specific 10DLC phone number or branded Sender ID across those accounts? Perhaps your development team needs to test an application in a sandbox account using a production-ready number, or you’re migrating a workload to a new account and need to ensure your customer communications aren’t disrupted. Centralizing your messaging resources across accounts improves efficiency and branding, while lowering the risk in compliance gaps..

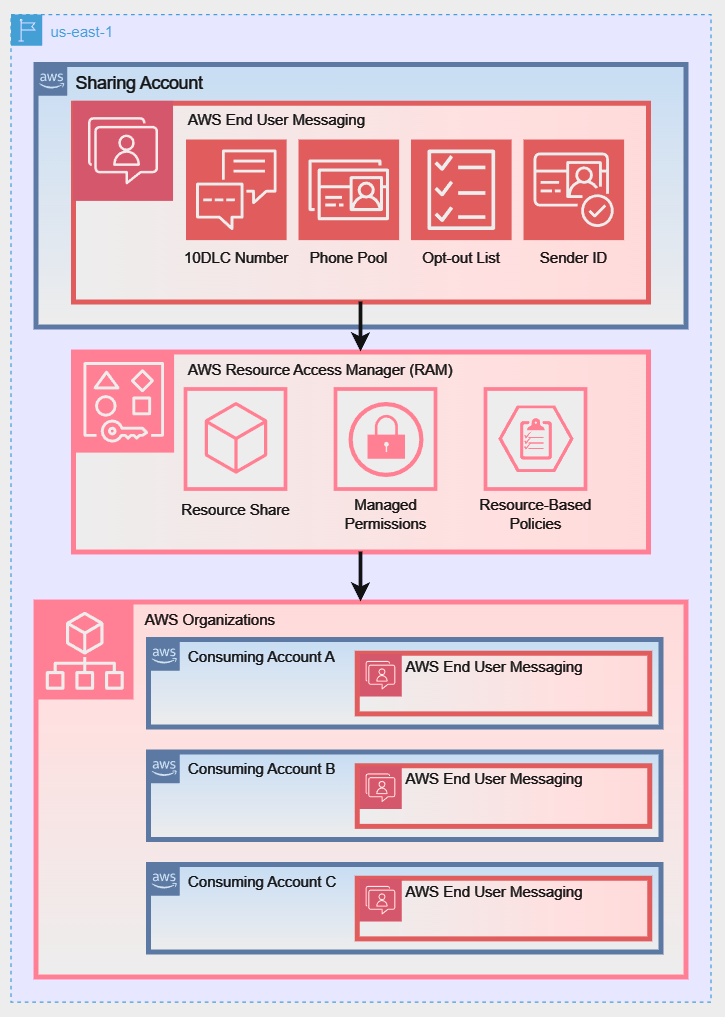
In this step-by-step guide, we will show how to solve this challenge by sharing your AWS End User Messaging resources across multiple AWS accounts using AWS Resource Access Manager (AWS RAM). By creating a single sharing account for your messaging resources—like phone numbers, Sender IDs, and opt-out lists—and securely sharing them with your other “consuming” accounts, you can build a more efficient, secure, and scalable communication platform.

Common Use Cases for Resource Sharing

Important: resource sharing with AWS RAM is a regional feature. You can only share resources with accounts within the same AWS Region where those resources are located.

Centralizing and sharing resources is a powerful pattern that addresses several common customer needs:

  • Testing in a Sandbox Environment: Allows development teams to test applications using production-ready phone numbers or Sender IDs in an isolated sandbox account, without giving them access to production configurations.
  • Simplified Registration and Onboarding: Share an existing pre-registered 10DLC number or Sender ID with a new account that has not yet completed its own registration process, enabling it to start sending messages more quickly.
  • Seamless Account Transitions: When migrating an application or workload to a new AWS account, you can share the existing origination identities. This makes certain that your phone numbers and Sender IDs remain consistent during the transition, preventing any disruption to your customer-facing communications.

This guide will walk you through the step-by-step process of sharing your AWS End User Messaging resources.

Shareable AWS End User Messaging Resources

You can share the following AWS End User Messaging resources using AWS RAM:

  • Phone Numbers: Share your dedicated short codes, 10DLCs, long codes, and toll-free numbers. This allows different accounts to send messages using a centralized pool of numbers.
  • Sender IDs: Share alphanumeric sender IDs to maintain consistent branding in one-way SMS messages across your accounts.
  • Opt-out Lists: Centralize your opt-out management to ensure regulatory compliance. When a user opts out of messaging from one account, they are opted out across all accounts using that shared list. This is especially powerful when used with pools, as you can associate a pool with a specific opt-out list, ensuring all numbers in that pool adhere to the same primary list. As a best practice, you should create and share a dedicated opt-out list rather than relying on the default list for each account.
  • Pools: Share your pools of phone numbers and sender IDs to manage origination identities at scale. Pools provide benefits like automatic failover and apply settings like opt-out lists or two-way SMS configurations to the entire pool.
    • Important: for a shared Opt-out list or pool to be functional, all of its member resources (the phone numbers and/or Sender IDs within it) must also be included in the same AWS RAM resource share.

Understanding AWS RAM Fundamentals

Before sharing your End User Messaging resources, it’s essential to understand the core concepts of AWS RAM.

  • Resource Share: This is the central component in AWS RAM. A resource share consists of three elements:
    • The resources to be shared (such as phone numbers, or opt-out lists).
    • The principals (AWS accounts, OUs, or an entire organization) with whom you are sharing.
    • The managed permissions that define what actions the principals can perform on the shared resources.

Important: The supported resources of AWS End User Messaging are shareable with AWS accounts, Organizations, and OUs, but not with individual AWS Identity and Access Management (IAM) roles or users. This restriction ensures that resource sharing remains at the account level, maintaining clear boundaries and simplifying access management for your End User Messaging infrastructure.

  • Sharing Account vs. Consuming Account:
    • The sharing account (or owner account) is the AWS account that owns the resources and creates the resource share.
    • When a principal (such as an AWS account) is granted access to a resource share, it becomes a consuming account. It can use the shared resources according to the permissions granted and pays for its own usage of those resources, not for the resources themselves. For example: The consuming account pays for the volume of SMS sent by a shared number but the sharing account pays for any fees associated with owning that actual number.
  • AWS Organizations Integration: While you can share resources with individual AWS accounts, the most powerful way to use AWS RAM is in conjunction with AWS Organizations. This service allows you to centrally manage and govern multiple AWS accounts under a single umbrella. When you enable sharing within your organization, you can share resources with all accounts in the organization, or with specific Organizational Units (OUs), seamlessly and without needing to send and accept individual invitations. This sharing is only possible between accounts that reside in the same AWS Region.
  • Managed Permissions: AWS RAM uses managed permissions to control access.
    • AWS managed permissions are predefined permission sets created and maintained by AWS for common use cases. For AWS End User Messaging, the key permission is AWSRAMDefaultPermissionSmsVoice, which allows consumers to use the resources for sending messages but not for deleting or modifying them.
    • Customer managed permissions can be created for more granular control over shared resources.
  • Resource-Based Policies: Behind the scenes, AWS RAM works by creating and managing resource-based policies for you. These policies are what actually grant the consuming accounts access to the shared resources.

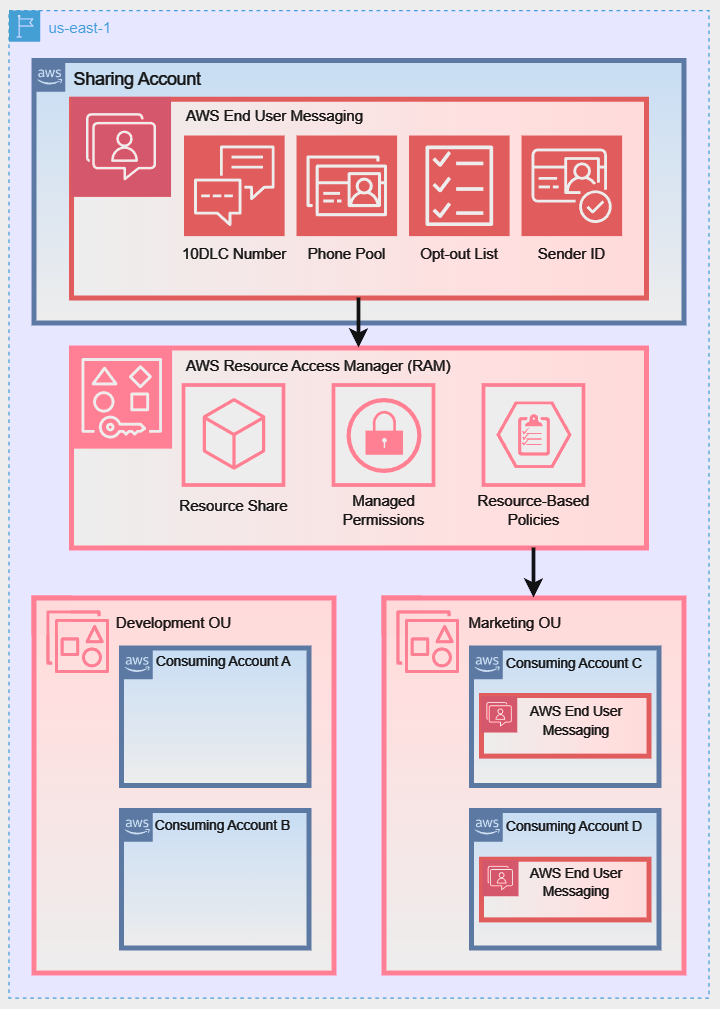
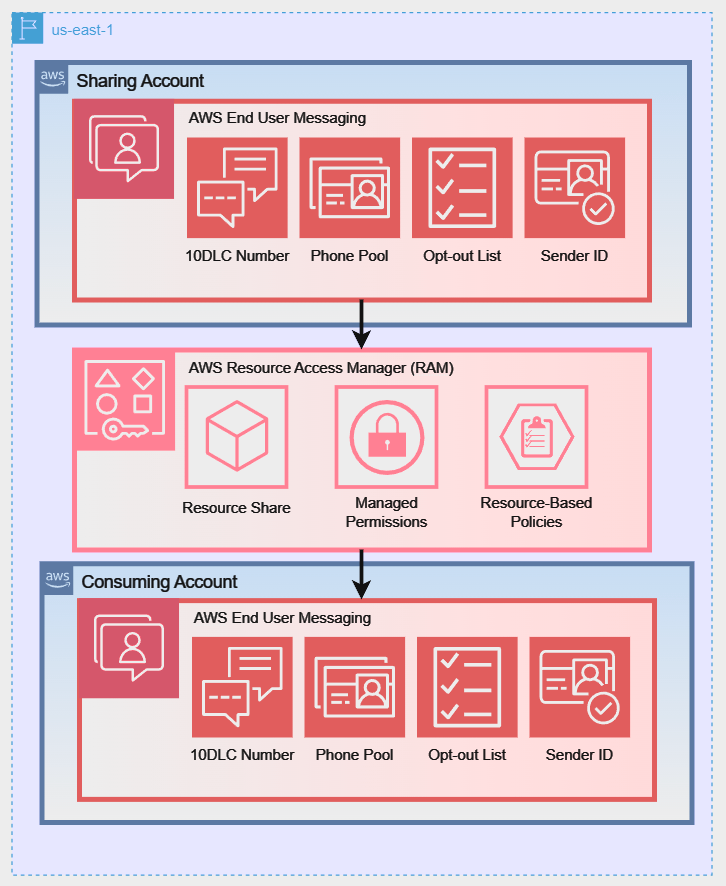
To better illustrate these sharing models, the following diagrams show how a Sharing Account can share its AWS End User Messaging resources using different strategies:

Diagram 1: Direct Account-to-Account Sharing:

Diagram 2: Sharing with an Entire AWS Organization:

Diagram 3: Sharing with a Specific Organizational Unit (OU):

Prerequisites and Setup

For the following walkthrough, we will demonstrate how to configure the setup for Diagram 1: Direct Account-to-Account Sharing. However, the steps for managing and using the resource share are similar for all three scenarios. Before you begin, ensure your environment is set up correctly.

Note for AWS Organizations Users: When your account is managed by AWS Organizations, you can take advantage of that to share resources more easily. With or without Organizations, a user can share with individual accounts. However, if your account is in an organization, then you can share with individual accounts, or with all accounts in the organization or in an OU without having to enumerate each account.

If you plan to share resources using AWS Organizations (as shown in Diagram 2 or Diagram 3), you must complete the following prerequisite steps from your organization’s management account before creating a resource share:

1. Enable all features in your organization:

aws organizations enable-all-features

2. Enable resource sharing with AWS RAM: This creates the necessary service-linked role.

aws ram enable-sharing-with-aws-organization

1. Required IAM Permissions

The IAM user or role performing these actions needs permissions for both AWS RAM and AWS End User Messaging. The following policy grants the necessary permissions to manage resource shares.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "RAMResourceShareManagement",
            "Effect": "Allow",
            "Action": [
                "ram:UpdateResourceShare",
                "ram:DeleteResourceShare",
                "ram:AssociateResourceShare",
                "ram:DisassociateResourceShare"
            ],
            "Resource": "arn:aws:ram:*:*:resource-share/*"
        },
        {
            "Sid": "DiscoveryAndCreationPermissions",
            "Effect": "Allow",
            "Action": [
                "ram:CreateResourceShare",
                "ram:GetResourceShares",
                "ram:ListResources",
                "organizations:ListAccounts",
                "organizations:DescribeOrganization",
                "pinpoint-sms-voice-v2:DescribePhoneNumbers",
                "pinpoint-sms-voice-v2:DescribeSenderIds",
                "pinpoint-sms-voice-v2:DescribeOptOutLists",
                "pinpoint-sms-voice-v2:DescribePools"
            ],
            "Resource": "*"
        }
    ]
}

Note on Least Privilege: This policy follows the security best practice of granting least privilege. The first statement scopes modification permissions to only AWS RAM resource shares. The second statement grants permissions for discovery actions (like Describe* and List*) and the ram:CreateResourceShare action, which require "Resource": "*" as they do not operate on a specific, pre-existing resource.

2. Regionality Requirement

Important Reminder: resource sharing with AWS RAM is a regional feature. You can only share resources with accounts within the same AWS Region where those resources are located.

For example, a resource in us-east-1 can only be shared with other accounts in us-east-1, regardless of where those accounts operate other resources. Ensure that the resources you intend to share and the accounts that you anticipate sharing with are each considering the same Region for this process.

Creating and Managing Resource Shares (Sharing Account Actions)

This section provides a step-by-step guide to sharing your resources using the AWS CLI. We will walk through creating a resource share, associating and disassociating resources, and checking the status of your shares.

Step 1: Create an Empty Resource Share

First, create the resource share. Think of this as an empty container. You will associate principals (the consuming accounts) and resources (the phone numbers, etc.) with this share.

In the command below, we will create a share named EUM-Shared-Resources for an external account.

# Create a resource share and grant default End User Messaging permissions # Replace 123456789012 with the consuming account's ID
aws ram create-resource-share \
    --name "EUM-Shared-Resources" \
    --principals "123456789012" \
    --permission-arns "arn:aws:ram::aws:permission/AWSRAMDefaultPermissionSmsVoice" \
    --allow-external-principals \
    --region us-east-1
  • --principals: Specify one or more AWS account IDs.
  • --allow-external-principals: This flag is required when sharing with accounts that are not part of your AWS Organization.

Expected Response: A successful command returns a JSON object describing the new resource share. Note that allowExternalPrincipals is now true.

{
    "resourceShare": {
        "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-example11111",
        "name": "EUM-Shared-Resources",
        "owningAccountId": "111122223333",
        "allowExternalPrincipals": false,
        "status": "ACTIVE",
        "tags": [],
        "featureSet": "STANDARD"
    }
}

For the following sections and when specifying resource ARNs, ensure you’re using the correct format for AWS End User Messaging resources:

  • Phone numbers: arn:aws:sms-voice:region:account-id:phone-number/phonenumber-id
  • Sender IDs: arn:aws:sms-voice:region:account-id:sender-id/senderid
  • Opt-out lists: arn:aws:sms-voice:region:account-id:opt-out-list/optoutlist-id
  • Pools: arn:aws:sms-voice:region:account-id:pool/pool-id

Replace ‘region‘, ‘account-id‘, and the specific resource IDs with your actual values.

Step 2: Associate Resources with the Share

Now that you have your “container,” you can add resources to it. The associate-resource-share command links one or more of your End User Messaging resources to the share you just created, making them available to the principals.

# Define the ARN of the resource share from the previous step
RESOURCE_SHARE_ARN="arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-111111111111"

# Associate a phone number and a pool with the share # Replace the resource-arns with your actual resource ARNs
aws ram associate-resource-share \
    --resource-share-arn "$RESOURCE_SHARE_ARN" \
    --resource-arns \
        "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" \
        "arn:aws:sms-voice:us-east-1:111122223333:pool/pool-b2c3d4e5" \
    --region us-east-1

Expected Response: A successful association returns a JSON object confirming the association and showing its status. The status will initially be ASSOCIATING and will transition to ASSOCIATED once complete.

Note: The association process is asynchronous. We’ll show you how to verify the completion status in the next step using the get-resource-shares and list-resources commands. It’s important to confirm the status has changed to ASSOCIATED before attempting to use the shared resources.

Step 3: Verify the Status and contents of the Share

Before making changes, it’s good practice to verify what’s in the share. Use get-resource-shares to check the status and list-resources to see the contents. This process helps ensure that all intended resources are properly associated and accessible to the principals you’ve designated.

# Verify the association status is ASSOCIATED
aws ram get-resource-shares \
    --resource-owner SELF \
    --name "EUM-Shared-Resources" \
    --association-status ASSOCIATED \
    --region us-east-1

Expected Response: If the command returns no results, wait a few moments and try again. The association process is typically quick but can sometimes take up to a few minutes.

{
    "resourceShares": [
        {
            "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/12345678-abcd-1234-efgh-111122223333",
            "name": "EUM-Shared-Resources",
            "owningAccountId": "111122223333",
            "allowExternalPrincipals": true,
            "status": "ACTIVE",
            "creationTime": "2023-07-01T12:00:00.000Z",
            "lastUpdatedTime": "2023-07-01T12:00:00.000Z",
            "featureSet": "STANDARD"
        }
    ]
}

Review the output carefully to ensure all intended resources are listed. If any resources are missing, you may need to reassociate them using the associate-resource-share command.

Expected Response (list-resources): This command will return a list of JSON objects, each representing a resource in the share.

# List the ARNs of all resources currently in the share
aws ram list-resources \
    --resource-owner SELF \
    --resource-share-arns "$RESOURCE_SHARE_ARN" \
    --region us-east-1

Review the output carefully to ensure all intended resources are listed. If any resources are missing, you may need to reassociate them using the associate-resource-share command.

# List the ARNs of all resources currently in the share
aws ram list-resources \
    --resource-owner SELF \
    --resource-share-arns "$RESOURCE_SHARE_ARN" \
    --region us-east-1

Expected Response (list-resources): This command will return a list of JSON objects, each representing a resource in the share.

{
    "resources": [
        {
            "arn": "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4",
            "type": "sms-voice:PhoneNumber",
            "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-example11111",
            "status": "AVAILABLE"
        },
        {
            "arn": "arn:aws:sms-voice:us-east-1:111122223333:pool/pool-b2c3d4e5",
            "type": "sms-voice:Pool",
            "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-example11111",
            "status": "AVAILABLE"
        }
    ]
}

Step 4: Disassociate Specific Resources from the Share

To stop sharing a specific resource, you use the disassociate-resource-share command. You must provide the ARN of the resource you wish to remove. This gives you granular control, allowing you to remove one resource while continuing to share others.

# Disassociate only the phone number from the share
aws ram disassociate-resource-share \
    --resource-share-arn "$RESOURCE_SHARE_ARN" \
    --resource-arns "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" \
    --region us-east-1

Expected Response: The response will be nearly identical to the associate response, confirming the disassociation request. The status will be DISASSOCIATING.

{
    "resourceShareAssociations": [
        {
            "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-example11111",
            "associatedEntity": "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4",
            "associationType": "RESOURCE",
            "status": "DISASSOCIATING",
            "external": false
        }
    ]
}

How to Use Shared Resources

Once resources are shared, users in the consuming accounts can discover and use them for sending messages.

Step 1: Discovering Shared Resources

From a consuming account, you can list resources that have been shared with you by using the --filters parameter in the describe-* commands.

Note: Shared resources are discoverable via the AWS CLI and SDKs but will not appear in the AWS Management Console of the consuming account. This is expected behavior, as the resources are owned by the sharing account.

# List phone numbers shared with your account
aws pinpoint-sms-voice-v2 describe-phone-numbers \
    --filters Name=shared-with-me,Values=true \
    --region us-east-1
# List sender IDs shared with your account
aws pinpoint-sms-voice-v2 describe-sender-ids \
--filters Name=shared-with-me,Values=true \
--region us-east-1

# List pools shared with your account
aws pinpoint-sms-voice-v2 describe-pools \
--filters Name=shared-with-me,Values=true \
--region us-east-1

# List shared opt-out lists with region specification
aws pinpoint-sms-voice-v2 describe-opt-out-lists \
--filters Name=shared-with-me,Values=true \
--region us-east-1

Expected Response: The command returns a JSON object listing the shared resources, including their ARNs, which you will need for sending messages.

{
    "PhoneNumbers": [
        {
            "PhoneNumberArn": "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4",
            "PhoneNumberId": "phonenumber-a1b2c3d4",
            "PhoneNumber": "+12065550100",
            "Status": "ACTIVE",
            "MessageType": "TRANSACTIONAL",
            "TwoWayEnabled": true,
            "CreatedTimestamp": "2023-10-26T14:34:56.123Z"
        }
    ]
}

Step 2: Sending Messages with Shared Resources

Important: When using shared resources, consuming accounts must specify the full ARN of the shared resource in API calls. This differs from resource owners, who can use either the resource ID, ARN, or the number directly. You can specify the ARN of an individual phone number or a pool as the origination-identity.

# Send an SMS using a shared Phone Number ARN (consuming account MUST use ARN)
aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+12065550199" \
    --origination-identity "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" \
    --message-body "Hello from a shared number!" \
    --region us-east-1

# Send an SMS using a shared Pool ARN (consuming account MUST use ARN)
aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+12065550199" \
    --origination-identity "arn:aws:sms-voice:us-east-1:111122223333:pool/pool-b2c3d4e5" \
    --message-body "Hello from a shared pool!" \
    --region us-east-1

Expected Response: A successful send-text-message call will return a MessageId, which confirms that the service has accepted the message for delivery.

{
    "MessageId": "a1b2c3d4-5678-90ab-cdef-example22222"
}

Message Delivery Reporting:

Once a message is sent, understanding its delivery status is crucial for ensuring your communications are effective. AWS End User Messaging provides several mechanisms for tracking message delivery, giving you a multi-layered approach to reporting.

Delivery Receipts (DLRs):

For traditional, carrier-provided Delivery Receipts (DLRs), which can sometimes take up to 72 hours to be returned, you must configure an event destination. This is the most common method for confirming that a message has reached the recipient’s handset, and is achieved through a Configuration Set.

For shared resources:

  • The configuration set must be created and managed in the sharing account.
  • The consuming account must then reference the ARN of the configuration set when sending messages.
# Example for consuming account
aws pinpoint-sms-voice-v2 send-text-message 
    --destination-phone-number "+12065550199" 
    --origination-identity "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" 
    --message-body "Hello from a shared number!" 
    --configuration-set-name "arn:aws:sms-voice:us-east-1:111122223333:configuration-set/MyConfigSet" 
    --region us-east-1

For a detailed walkthrough, see our companion blog post, How to Send SMS Using Configuration Sets with AWS End User Messaging.

Message Feedback:

For more immediate, application-driven insights, you can use the Message Feedback feature. This allows you to programmatically mark messages as “delivered” based on a user’s action, such as using a one-time password (OTP) or clicking a link in the message. This provides a real-time confirmation loop that is independent of carrier DLRs.

Amazon CloudWatch:

To monitor these events at scale, you can stream them to Amazon CloudWatch Logs to track key performance indicators like the number of messages sent and delivered, and to set up alerts based on your specific business needs.

To set up comprehensive reporting:

  1. Configure an event destination for DLRs and detailed status events.
  2. Set up CloudWatch dashboards and alerts for ongoing monitoring.

This multi-layered approach provides both immediate feedback and long-term delivery insights, allowing you to optimize your messaging strategy and quickly identify potential delivery issues.

Troubleshooting Common Issues

  • Permission Denied Errors: If a consuming account cannot access a shared resource, verify that the consuming account’s IAM policies include the necessary permissions. Here’s an example policy:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "pinpoint-sms-voice-v2:SendTextMessage",
                "pinpoint-sms-voice-v2:SendVoiceMessage",
                "pinpoint-sms-voice-v2:DescribePhoneNumbers",
                "pinpoint-sms-voice-v2:DescribeSenderIds",
                "pinpoint-sms-voice-v2:DescribeOptOutLists",
                "pinpoint-sms-voice-v2:DescribePools"
            ],
            "Resource": "*"
        }
    ]
}
  • Resource Not Visible: Remember that shared resources do not appear in the consuming account’s AWS Management Console. If the describe-* commands with the shared-with-me filter return no results, ensure the resource share status is ACTIVE in the sharing account.
    • If sharing via AWS Organizations, confirm the consuming account is correctly placed in the specified OU. You can find more information on managing OUs in the AWS Organizations User Guide.
  • CLI Command Fails: If a command fails with a “not found” or “invalid parameter” error, it is often due to an incorrect ARN. Double-check that the ARNs for resources, principals, and the resource share itself are correct. A Permission Denied error, on the other hand, points to an IAM policy issue..

Best Practices and Considerations

  • Security: Always follow the principle of least privilege. Use AWS managed permissions like AWSRAMDefaultPermissionSmsVoice where possible and create customer-managed permissions only for specific, granular requirements.
  • Cost: The sharing account is billed for provisioning the resources (e.g., the monthly cost of a phone number). Consuming accounts are billed for their usage of those shared resources (e.g., the cost per message sent). There are no additional costs for using AWS RAM.
  • Throughput and Quotas: Resource throughput quotas (e.g., messages per second) are shared along with the resource. High volume sending from multiple consuming accounts using the same shared number or pool, could collectively hit the service quota, which may result in throttling. Plan your usage accordingly or request quota increases if necessary.

Conclusion

This guide has equipped you to centralize your AWS End User Messaging resources using AWS Resource Access Manager. By implementing this strategy, you can directly address the common challenges of a multi-account environment: maintaining consistent branding with shared Sender IDs, ensuring comprehensive compliance with centralized opt-out lists, and reducing operational overhead by managing resources in one place.

We have walked through the entire lifecycle, from the initial prerequisites in AWS Organizations and IAM, to the step-by-step CLI commands for creating shares, associating resources, and enabling consuming accounts to use them. By applying these techniques and keeping the best practices for security and throughput in mind, you are now able to build a more efficient, secure, and scalable communication platform across your entire AWS ecosystem.
Subverting AIOps Systems Through Poisoned Input Data

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/subverting-aiops-systems-through-poisoned-input-data.html

In this input integrity attack against an AI system, researchers were able to fool AIOps tools:

AIOps refers to the use of LLM-based agents to gather and analyze application telemetry, including system logs, performance metrics, traces, and alerts, to detect problems and then suggest or carry out corrective actions. The likes of Cisco have deployed AIops in a conversational interface that admins can use to prompt for information about system performance. Some AIOps tools can respond to such queries by automatically implementing fixes, or suggesting scripts that can address issues.

These agents, however, can be tricked by bogus analytics data into taking harmful remedial actions, including downgrading an installed package to a vulnerable version.

The paper: “When AIOps Become “AI Oops”: Subverting LLM-driven IT Operations via Telemetry Manipulation“:

Abstract: AI for IT Operations (AIOps) is transforming how organizations manage complex software systems by automating anomaly detection, incident diagnosis, and remediation. Modern AIOps solutions increasingly rely on autonomous LLM-based agents to interpret telemetry data and take corrective actions with minimal human intervention, promising faster response times and operational cost savings.

In this work, we perform the first security analysis of AIOps solutions, showing that, once again, AI-driven automation comes with a profound security cost. We demonstrate that adversaries can manipulate system telemetry to mislead AIOps agents into taking actions that compromise the integrity of the infrastructure they manage. We introduce techniques to reliably inject telemetry data using error-inducing requests that influence agent behavior through a form of adversarial reward-hacking; plausible but incorrect system error interpretations that steer the agent’s decision-making. Our attack methodology, AIOpsDoom, is fully automated—combining reconnaissance, fuzzing, and LLM-driven adversarial input generation—and operates without any prior knowledge of the target system.

To counter this threat, we propose AIOpsShield, a defense mechanism that sanitizes telemetry data by exploiting its structured nature and the minimal role of user-generated content. Our experiments show that AIOpsShield reliably blocks telemetry-based attacks without affecting normal agent performance.

Ultimately, this work exposes AIOps as an emerging attack vector for system compromise and underscores the urgent need for security-aware AIOps design.

Zero-Day Exploit in WinRAR File

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/zero-day-exploit-in-winrar-file.html

A zero-day vulnerability in WinRAR is being exploited by at least two Russian criminal groups:

The vulnerability seemed to have super Windows powers. It abused alternate data streams, a Windows feature that allows different ways of representing the same file path. The exploit abused that feature to trigger a previously unknown path traversal flaw that caused WinRAR to plant malicious executables in attacker-chosen file paths %TEMP% and %LOCALAPPDATA%, which Windows normally makes off-limits because of their ability to execute code.

More details in the article.

Eavesdropping on Phone Conversations Through Vibrations

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/eavesdropping-on-phone-conversations-through-vibrations.html

Researchers have managed to eavesdrop on cell phone voice conversations by using radar to detect vibrations. It’s more a proof of concept than anything else. The radar detector is only ten feet away, the setup is stylized, and accuracy is poor. But it’s a start.

Trojans Embedded in .svg Files

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/trojans-embedded-in-svg-files.html

Porn sites are hiding code in .svg files:

Unpacking the attack took work because much of the JavaScript in the .svg images was heavily obscured using a custom version of “JSFuck,” a technique that uses only a handful of character types to encode JavaScript into a camouflaged wall of text.

Once decoded, the script causes the browser to download a chain of additional obfuscated JavaScript. The final payload, a known malicious script called Trojan.JS.Likejack, induces the browser to like a specified Facebook post as long as a user has their account open.

“This Trojan, also written in Javascript, silently clicks a ‘Like’ button for a Facebook page without the user’s knowledge or consent, in this case the adult posts we found above,” Malwarebytes researcher Pieter Arntz wrote. “The user will have to be logged in on Facebook for this to work, but we know many people keep Facebook open for easy access.”

This isn’t a new trick. We’ve seen Trojaned .svg files before.

LLM Coding Integrity Breach

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/llm-coding-integrity-breach.html

Here’s an interesting story about a failure being introduced by LLM-written code. Specifically, the LLM was doing some code refactoring, and when it moved a chunk of code from one file to another it changed a “break” to a “continue.” That turned an error logging statement into an infinite loop, which crashed the system.

This is an integrity failure. Specifically, it’s a failure of processing integrity. And while we can think of particular patches that alleviate this exact failure, the larger problem is much harder to solve.

Davi Ottenheimer comments.

The Compliance Arms Race: What GovRAMP Means for SLED, Cloud Vendors, and the Rest of Us

Post Syndicated from Kari Rivas original https://www.backblaze.com/blog/the-compliance-arms-race-what-govramp-means-for-sled-cloud-vendors-and-the-rest-of-us/

A decorative image showing a server, a NAS, and a computer.

If you’ve spent any time sourcing, evaluating, or speculating about cloud services in the public sector lately, you’ve likely felt it: the arms race happening in compliance. Courting customers from schools to statehouses to national labs, more and more cloud vendors are racing to pin the next security badge to their lapel—GovRAMP (formerly known as StateRAMP), TX-RAMP, FedRAMP, SOC 2, and on and on.

And while it might feel like a compliance bingo card, there’s real strategy and real consequences behind this sprint. At the heart of it all is the SLED market (state and local government, and education)—a sprawling patchwork of institutions tasked with safeguarding citizen data and taxpayer trust, all while operating with limited resources and infrastructure budgets.

Let’s talk about why this compliance arms race exists, what it means for buyers and vendors alike, and how we at Backblaze are choosing to compete not just with checkboxes, but with character.

Why does SLED even need unified standards?

Public sector IT has long been a security quilt. Some agencies stitched up with advanced defenses, others more… threadbare. While some may have advanced security tooling, a K–12 school district might still be running on legacy systems and duct tape. Yet both manage data that’s increasingly digital, distributed, and vulnerable.

The result? Inconsistent practices and rising risks. Enter: GovRAMP.

What is GovRAMP?

Short for Government Risk and Authorization Management Program, GovRAMP was customized to standardize cloud security for state and local agencies. It’s actually based on the same set of controls for FedRAMP—controls derived from the National Institute of Standards and Technology (NIST) SP 800-53, a catalog of controls for organizations to manage cybersecurity and privacy risk. GovRAMP ensures that even the smallest public institutions can procure secure IT solutions without reinventing the wheel every time.

GovRAMP was originally launched as StateRAMP, but has since grown beyond state lines, evolving into a broader framework adopted by local governments and school systems. Today, it’s a rigorous, independent audit program that holds vendors to a high set of security controls. Translation: If a vendor is GovRAMP-authorized, they’re playing in the big leagues of cloud security.

The alphabet soup of compliance: TX-RAMP, GovRAMP, FedRAMP

If you’re in Texas, you’re probably familiar with TX-RAMP, the state’s specific compliance framework. The good news? GovRAMP and TX-RAMP are closely aligned. At Backblaze, our GovRAMP Progressing Snapshot status qualifies us for TX-RAMP Provisional Authorization as well—one less hurdle for Texas agencies seeking secure, scalable cloud storage.

As for FedRAMP, it remains the gold standard for federal data, but for the vast majority of public sector orgs, including most SLED agencies, it’s simply unnecessary.

How GovRAMP streamlines cloud sourcing

Here’s where the compliance arms race actually makes things easier: Once a vendor is authorized through GovRAMP, SLED buyers can trust that the solution meets certain security standards, saving months of one-off vetting, paperwork, and duplicated audits. In a procurement environment plagued by inefficiency, that’s no small thing.

Especially now, as budgets tighten and AI-driven everything drives demand for flexible infrastructure, reducing sourcing friction matters more than ever.

Going beyond checklists: What buyers should really look for

Checkboxes alone don’t guarantee real-world resilience. Compliance can become its own form of security theater. It looks good on paper but falls short in practice. That’s why buyers should dig deeper.

Look for vendors who not only pass audits but live and breathe their controls. That means going beyond annual assessments and embracing security as a continuous, integrated discipline. The best partners are transparent, proactive, and thoughtful about risk—not just checking boxes, but building real-world resilience. Here are a few signs to look for:

  • Continuous monitoring and internal audits: They treat compliance as an ongoing process, not a once-a-year scramble.
  • Clear, accessible documentation: Security policies, certifications, and standardized independent attestations are available (under NDA if needed), not locked in a black box.
  • Transparent data practices: They’re upfront about where your data lives, who can access it, and what happens in the event of an incident. 
  • Responsive support: You can communicate with real people who understand your risk profile—not just surface-level answers or automated replies.
  • Affordable recoveries: They don’t make recovering your data prohibitively expensive. Look at their egress policies and price out what it would actually cost to retrieve your data.

When you’re responsible for protecting sensitive data, it’s not enough to be compliant. You need a partner who’s disciplined, trustworthy, and invested in your resilience.

The Backblaze approach: Rigor, transparency, and trust

Pursuing authorizations like GovRAMP and TX-RAMP isn’t easy, but it’s the right thing to do and we’re committed to the process. We believe public sector buyers deserve cloud partners who understand their constraints, meet them where they are, and still bring best-in-class solutions to the table.

But more than that, we’re not stopping at frameworks. Compliance is a floor, not a ceiling. We’ve built our platform on decades of operational rigor and security discipline—not to impress auditors, but to earn your trust. And we’ve structured our products to enable security best practices, not hinder them, including 3x free egress for disaster recovery.

So yes, we’re proudly in the compliance race. But we’re not just chasing badges. We’re building something secure, sustainable, and ready for whatever comes next.

Want to learn more about our GovRAMP journey or how Backblaze supports public sector cloud transformation? Reach out to our Sales team.

The post The Compliance Arms Race: What GovRAMP Means for SLED, Cloud Vendors, and the Rest of Us appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

SIGINT During World War II

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/sigint-during-world-war-ii.html

The NSA and GCHQ have jointly published a history of World War II SIGINT: “Secret Messengers: Disseminating SIGINT in the Second World War.” This is the story of the British SLUs (Special Liaison Units) and the American SSOs (Special Security Officers).

The “Incriminating Video” Scam

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/the-incriminating-video-scam.html

A few years ago, scammers invented a new phishing email. They would claim to have hacked your computer, turned your webcam on, and videoed you watching porn or having sex. BuzzFeed has an article talking about a “shockingly realistic” variant, which includes photos of you and your house—more specific information.

The article contains “steps you can take to figure out if it’s a scam,” but omits the first and most fundamental piece of advice: If the hacker had incriminating video about you, they would show you a clip. Just a taste, not the worst bits so you had to worry about how bad it could be, but something. If the hacker doesn’t show you any video, they don’t have any video. Everything else is window dressing.

I remember when this scam was first invented. I calmed several people who were legitimately worried with that one fact.

Blue/Green Deployments with Amazon Elastic Container Service

Post Syndicated from Nathan Taber original https://aws.amazon.com/blogs/compute/bluegreen-deployments-with-amazon-ecs/

This post and accompanying code was generously contributed by:

Jeremy Cowan
Solutions Architect
Anuj Sharma
DevOps Cloud Architect
Peter Dalbhanjan
Solutions Architect

Deploying software updates in traditional non-containerized environments is hard and fraught with risk. When you write your deployment package or script, you have to assume that the target machine is in a particular state. If your staging environment is not an exact mirror image of your production environment, your deployment could fail. These failures frequently cause outages that persist until you re-deploy the last known good version of your application. If you are an Operations Manager, this is what keeps you up at night.

Increasingly, customers want to do testing in production environments without exposing customers to the new version until the release has been vetted. Others want to expose a small percentage of their customers to the new release to gather feedback about a feature before it’s released to the broader population. This is often referred to as canary analysis or canary testing. In this post, I introduce patterns to implement blue/green and canary deployments using Application Load Balancers and target groups.

If you’d like to try this approach to blue/green deployments, we have open sourced the code and AWS CloudFormation templates in the ecs-blue-green-deployment GitHub repo. The workflow builds an automated CI/CD pipeline that deploys your service onto an ECS cluster and offers a controlled process to swap target groups when you’re ready to promote the latest version of your code to production. You can quickly set up the environment in three steps and see the blue/green swap in action. We’d love for you to try it and send us your feedback!

What are blue/green deployments?

Blue/green deployments are a type of immutable deployment used to deploy software updates with less risk by creating two separate environments, blue and green. “Blue” is the current running version of your application and “green” is the new version of your application you will deploy.

This type of deployment gives you an opportunity to test features in the green environment without impacting the current running version of your application. When you’re satisfied that the green version is working properly, you can gradually reroute the traffic from the old blue environment to the new green environment by modifying DNS. By following this method, you can update and roll back features with near zero downtime.

A typical blue/green deployment involves shifting traffic between 2 distinct environments.

This ability to quickly roll traffic back to the still-operating blue environment is one of the key benefits of blue/green deployments. With blue/green, you should be able to roll back to the blue environment at any time during the deployment process. This limits downtime to the time it takes to realize there’s an issue in the green environment and shift the traffic back to the blue environment. Furthermore, the impact of the outage is limited to the portion of traffic going to the green environment, not all traffic. If the blast radius of deployment errors is reduced, so is the overall deployment risk.

Containers make it simpler

Historically, blue/green deployments were not often used to deploy software on-premises because of the cost and complexity associated with provisioning and managing multiple environments. Instead, applications were upgraded in place.

Although this approach worked, it had several flaws, including the ability to roll back quickly from failures. Rollbacks typically involved re-deploying a previous version of the application, which could affect the length of an outage caused by a bad release. Fixing the issue took precedence over the need to debug, so there were fewer opportunities to learn from your mistakes.

Containers can ease the adoption of blue/green deployments because they’re easily packaged and behave consistently as they’re moved between environments. This consistency comes partly from their immutability. To change the configuration of a container, update its Dockerfile and rebuild and re-deploy the container rather than updating the software in place.

Containers also provide process and namespace isolation for your applications, which allows you to run multiple versions of them side by side on the same Docker host without conflicts. Given their small sizes relative to virtual machines, you can binpack more containers per host than VMs. This lets you make more efficient use of your computing resources, reducing the cost of blue/green deployments.

Fully Managed Updates with Amazon ECS

Amazon Elastic Container Service (ECS) performs rolling updates when you update an existing Amazon ECS service. A rolling update involves replacing the current running version of the container with the latest version. The number of containers Amazon ECS adds or removes from service during a rolling update is controlled by adjusting the minimum and maximum number of healthy tasks allowed during service deployments.

When you update your service’s task definition with the latest version of your container image, Amazon ECS automatically starts replacing the old version of your container with the latest version. During a deployment, Amazon ECS drains connections from the current running version and registers your new containers with the Application Load Balancer as they come online.

Target groups

A target group is a logical construct that allows you to run multiple services behind the same Application Load Balancer. This is possible because each target group has its own listener.

When you create an Amazon ECS service that’s fronted by an Application Load Balancer, you have to designate a target group for your service. Ordinarily, you would create a target group for each of your Amazon ECS services. However, the approach we’re going to explore here involves creating two target groups: one for the blue version of your service, and one for the green version of your service. We’re also using a different listener port for each target group so that you can test the green version of your service using the same path as the blue service.

With this configuration, you can run both environments in parallel until you’re ready to cut over to the green version of your service. You can also do things such as restricting access to the green version to testers on your internal network, using security group rules and placement constraints. For example, you can target the green version of your service to only run on instances that are accessible from your corporate network.

Swapping Over

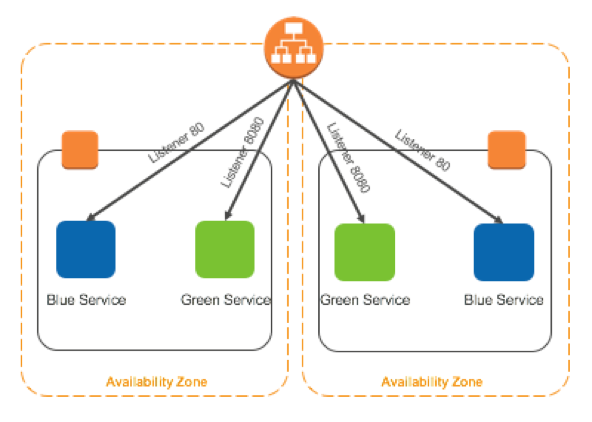
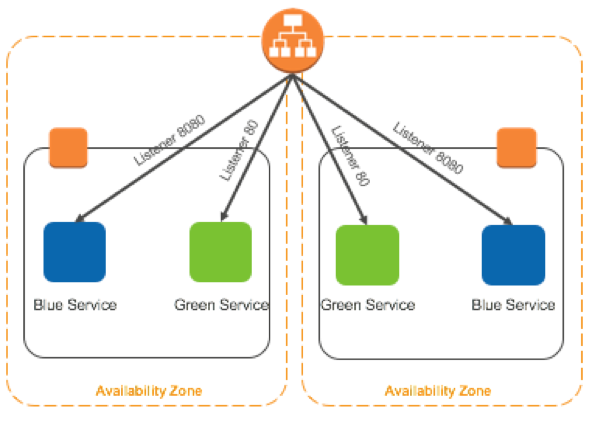
When you’re ready to replace the old blue service with the new green service, call the ModifyListener API operation to swap the listener’s rules for the target group rules. The change happens within a few seconds. Afterward, the green service is running in the target group with the port 80 listener and the blue service is running in the target group with the port 8080 listener. The diagram below is an illustration of the approach described.

Scenario

Two services are defined, each with their own target group registered to the same Application Load Balancer but listening on different ports. Deployment is completed by swapping the listener rules between the two target groups.

The second service is deployed with a new target group listening on a different port but registered to the same Application Load Balancer.

By using 2 listeners, requests to blue services are directed to the target group with the port 80 listener, while requests to the green services are directed to target group with the port 8080 listener.

After automated or manual testing, the deployment can be completed by swapping the listener rules on the Application Load Balancer and sending traffic to the green service.

Caveats

There are a few caveats to be mindful of when using this approach. This method:

  • Assumes that your application code is completely stateless. Store state outside of the container.
  • Doesn’t gracefully drain connections. The swapping of target groups is sudden and abrupt. Therefore, be cautious about using this approach if your service has long-running transactions.
  • Doesn’t allow you to perform canary deployments. While the method gives you the ability to quickly switch between different versions of your service, it does not allow you to divert a portion of the production traffic to a canary or control the rate at which your service is deployed across the cluster.

Canary testing

While this type of deployment automates much of the heavy lifting associated with rolling deployments, it doesn’t allow you to interrupt the deployment if you discover an issue midstream. Rollbacks using the standard Amazon ECS deployment require updating the service’s task definition with the last known good version of the container. Then, you wait for Amazon ECS to schedule and deploy it across the cluster. If the latest version introduces a breaking change that went undiscovered during testing, this might be too slow.

With canary testing, if you discover the green environment is not operating as expected, there is no impact on the blue environment. You can route traffic back to it, minimizing impaired operation or downtime, and limiting the blast radius of impact.

This type of deployment is particularly useful for A/B testing where you want to expose a new feature to a subset of users to get their feedback before making it broadly available.

For canary style deployments, you can use a variation of the blue/green swap that involves deploying the blue and the green service to the same target group. Although this method is not as fast as the swap, it allows you to control the rate at which your containers are replaced by adjusting the task count for each service. Furthermore, it gives you the ability to roll back by adjusting the number of tasks for the blue and green services respectively. Unlike the swap approach described above, connections to your containers are drained gracefully. We plan to address canary style deployments for Amazon ECS in a future post.

Conclusion

With AWS, you can operationalize your blue/green deployments using Amazon ECS, an Application Load Balancer, and target groups. I encourage you to adapt the code published to the ecs-blue-green-deployment GitHub repo for your use cases and look forward to reading your feedback.

If you’re interested in learning more, I encourage you to read the Blue/Green Deployments on AWS and Practicing Continuous Integration and Continuous Delivery on AWS whitepapers.

If you have questions or suggestions, please comment below.

Google Project Zero Changes Its Disclosure Policy

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/google-project-zero-changes-its-disclosure-policy.html

Google’s vulnerability finding team is again pushing the envelope of responsible disclosure:

Google’s Project Zero team will retain its existing 90+30 policy regarding vulnerability disclosures, in which it provides vendors with 90 days before full disclosure takes place, with a 30-day period allowed for patch adoption if the bug is fixed before the deadline.

However, as of July 29, Project Zero will also release limited details about any discovery they make within one week of vendor disclosure. This information will encompass:

  • The vendor or open-source project that received the report
  • The affected product
  • The date the report was filed and when the 90-day disclosure deadline expires

I have mixed feelings about this. On the one hand, I like that it puts more pressure on vendors to patch quickly. On the other hand, if no indication is provided regarding how severe a vulnerability is, it could easily cause unnecessary panic.

The problem is that Google is not a neutral vulnerability hunting party. To the extent that it finds, publishes, and reduces confidence in competitors’ products, Google benefits as a company.

China Accuses Nvidia of Putting Backdoors into Their Chips

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/china-accuses-nvidia-of-putting-backdoors-into-their-chips.html

The government of China has accused Nvidia of inserting a backdoor into their H20 chips:

China’s cyber regulator on Thursday said it had held a meeting with Nvidia over what it called “serious security issues” with the company’s artificial intelligence chips. It said US AI experts had “revealed that Nvidia’s computing chips have location tracking and can remotely shut down the technology.”