Earlier this week, the Trump administration narrowed export controls on advanced semiconductors ahead of US-China trade negotiations. The administration is increasingly relying on export licenses to allow American semiconductor firms to sell their products to Chinese customers, while keeping the most powerful of them out of the hands of our military adversaries. These are the chips that power the artificial intelligence research fueling China’s technological rise, as well as the advanced military equipment underpinning Russia’s invasion of Ukraine.
American semiconductor firms are unwilling or unable to restrict the flow of semiconductors. Instead of investing in effective compliance mechanisms, these firms have consistently prioritized their bottom lines—a rational decision, given the fundamentally risky nature of the semiconductor industry.
We can’t afford to wait for semiconductor firms to catch up gradually. To create a robust regulatory environment in the semiconductor industry, both the US government and chip companies must take clear and decisive actions today and consistently over time.
Consider the financial services industry. Those companies are also heavily regulated, implementing US government regulations ranging from international sanctions to anti-money laundering. For decades, these companies have invested heavily in compliance technology. Large banks maintain teams of compliance employees, often numbering in the thousands.
The companies understand that by entering the financial services industry, they assume the responsibility to verify their customers’ identities and activities, refuse services to those engaged in criminal activity, and report certain activities to the authorities. They take these obligations seriously because they know they will face massive fines when they fail. Across the financial sector, the Securities and Exchange Commission imposed a whopping $6.4 billion in penalties in 2022. For example, TD Bank recently paid almost $2 billion in penalties because of its ineffective anti-money laundering efforts
An executive order issued earlier this year applied a similar regulatory model to potential “know your customer” obligations for certain cloud service providers.
If Trump’s new license-focused export controls are to be effective, the administration must increase the penalties for noncompliance. The Commerce Department’s Bureau of Industry and Security (BIS) needs to more aggressively enforce its regulations by sharply increasing penalties for export control violations.
BIS has been working to improve enforcement, as evidenced by this week’s news of a $95 million penalty against Cadence Design Systems for violating export controls on its chip design technology. Unfortunately, BIS lacks the people, technology, and funding to enforce these controls across the board.
The Trump administration should also use its bully pulpit, publicly naming companies that break the rules and encouraging American firms and consumers to do business elsewhere. Regulatory threats and bad publicity are the only ways to force the semiconductor industry to take export control regulations seriously and invest in compliance.
With those threats in place, American semiconductor firms must accept their obligation to comply with regulations and cooperate. They need to invest in strengthening their compliance teams and conduct proactive audits of their subsidiaries, their customers, and their customers’ customers.
Firms should elevate risk and compliance voices onto their executive leadership teams, similar to the chief risk officer role found in banks. Senior leaders need to devote their time to regular progress reviews focused on meaningful, proactive compliance with export controls and other critical regulations, thereby leading their organizations to make compliance a priority.
As the world becomes increasingly dangerous and America’s adversaries become more emboldened, we need to maintain stronger control over our supply of critical semiconductors. If Russia and China are allowed unfettered access to advanced American chips for their AI efforts and military equipment, we risk losing the military advantage and our ability to deter conflicts worldwide. The geopolitical importance of semiconductors will only increase as the world becomes more dangerous and more reliant on advanced technologies—American security depends on limiting their flow.
This essay was written with Andrew Kidd and Celine Lee, and originally appeared in The National Interest.
An Arizona woman was sentenced to eight-and-a-half years in prison for her role helping North Korean workers infiltrate US companies by pretending to be US workers.
According to court documents, Chapman hosted the North Korean IT workers’ computers in her own home between October 2020 and October 2023, creating a so-called “laptop farm” which was used to make it appear as though the devices were located in the United States.
The North Koreans were hired as remote software and application developers with multiple Fortune 500 companies, including an aerospace and defense company, a major television network, a Silicon Valley technology company, and a high-profile company.
As a result of this scheme, they collected over $17 million in illicit revenue paid for their work, which was shared with Chapman, who processed their paychecks through her financial accounts.
“Chapman operated a ‘laptop farm’ where she received and hosted computers from the U.S. companies her home, so that the companies would believe the workers were in the United States,” the Justice Department said on Thursday.
“Chapman also shipped 49 laptops and other devices supplied by U.S. companies to locations overseas, including multiple shipments to a city in China on the border with North Korea. More than 90 laptops were seized from Chapman’s home following the execution of a search warrant in October 2023.”
Аркадий Хайт е съветски и руски писател, хуморист, сценарист. Половината от писателското дуо Курляндский и Хайт – автори на сценария за любимия на децата по съветско време „Ну, погоди!“ и купища хумористични разкази.
Днес мярнах в Нета една негова история, която не мога да се сдържа да не открадна и преведа. С уважение към таланта му – и таланта на леля Миня.
—-
Мина Мойсеевна, или просто леля Миня, беше съседка по жилище на мой приятел, режисьор в киностудия „Горки“. Той и ни запозна.
– Мина Мойсеевна, знаете ли кой е това? Това е Хайт!
– Е и какво? – беше отговорът ѝ. – Да застана „мирно“? Или да ходя да си мия врата?
– Не е нужно – казах аз. – Можете да ходите и с мръсен.
– Ой, какъв язвителен младеж! Жалко че не знаех, че ще имам толкова важен гост. Щях да взема нещо специално към чая. Вие как го предпочитате – без вишнево сладко или без ягодово?
– Без малиново, ако може.
– Разбира се? Имам всичко.
За сладкото, естествено, се бъзикаше. Имаше и сладко, и сладки, и бонбони – както си трябва в приличен еврейски дом. Понякога си видял човек за пръв път преди пет минути, а имаш усещането, че го познаваш цял живот. Точно такова чувство имах след първата ми среща с Мина Мойсеевна.
Като видя днес на сцената Клара Новикова като нейната леля Соня, чиито монолози ги пишат най-добрите хумористи, си мисля – ами леля Миня? На нея никой не ѝ пишеше репликите, тя си ги измисляше сама.
Помня – седим с нея, говорим си. Звънва изведнъж телефонът. Някой е сбъркал номера. Мъжки глас, който се чува из цялата стая, крещи:
– Къде съм попаднал?
– А къде сте се целили? – пита леля Миня.
Макар че беше по душа стопроцентова еврейка, не можеше да търпи разговори какви сме потресаващо умни:
– Ох, не ми мотайте главата. Племенникът ми например, евреин та дрънка, е тъп като онова място. Завърши тази година училище, и какво? С неговите познания може да влезе само в института „Склифосовски“.
(Руският еквивалент на института „Пирогов“ у нас – Григор.)
Специално почвах да я дразня:
– Ние не сме ли избран народ?
– Ние с вас – да! Но някои евреи май са ги избирали с пряко и тайно гласуване, като нашия Върховен съвет на СССР.
Време е да кажем какво работеше леля Миня. Беше професионална сватовница. Днес, в епохата на брачните обяви и електронните комуникации, тази професия изглежда забравена. Но не и за тези, които познаваха Мина Мойсеевна.
– Човек трябва да умее да си хвали стоката – казваше тя. – Рекламата е голяма работа. Погледнете кокошката като снесе яйце как кудкудяка, колко врява вдига. Патицата снася без нито един звук. А резултатът? Кокошите яйца ги купува всеки, а за пачите никой не е и чувал. Нямат звукова реклама!
Не знам как тя рекламираше своите женихи и невести, но клиентелата ѝ беше обширна. Телефонът не млъкваше от сутрин до вечер. Беше непрекъснато удоволствие да я слушаш как решава брачните дела.
– Ало? Какво? Да, помня ви, Володя. Та, какво търсите?… Млада? Красива? И какво още, богата? Не разбирам, на вас три жени ли ви трябват? Аха, една! Ама да има всичко това. Ясно. Извинете, а вие какъв сте? Каква ви е професията? Учител по зоология? Ми вие сте като лебед бе, скъпи. Един дълъг врат и голо дупе. Добре, звънете, ще ви търсим…
-Ало? Кой се обажда? Роза Григориевна? Буцкес ли ви пращаше? Много ми е приятно. А какво искате?… Жених? За кого, за внучката? Не? А за дъщерята ли? А, за вас! Интересно… Ако не е тайна, на колко години сте? 36? А преди колко години ги навършихте?… Добре, добре, ще търсим. Току-виж изкопаем нещо…
– Ало, Яков Абрамович ли е? Добре, че ви открих. Скъпи мой, и двамата прекрасно знаем, че дъщеря ви е отврат, която не ви дава да дишате. Ама и така, като ви доведа жених, не бива веднага да му целувате ръцете и да го наричате спасител. Веднага почват да подозират нещо!…
Казваше ми понякога:
– Жалко, че не те познавах по-рано. Щях да ти намеря хубава жена.
– Аз и сам съм си намерил.
– Не споря! Ама щях да ти намеря също такава, и плюс това еврейка.
– Ако толкова ви бива, защо не сте си намерили хубав мъж евреин?
– Я стига! Не ми сипвай сол в захарта. С моя Миша отдавна се разделихме.
– И защо, ако не е тайна?
– Хъркаше.
– Какво, за такава дреболия?!
– Да, ама той хъркаше всеки път с различна…
Когато Мина Мойсеевна навърши 75 години, тя взе най-важното решение в живота си – да емигрира в Израел. Всичките ѝ приятелки я убеждаваха да се откаже:
– Миночка, къде сте тръгнала на тия години? Да живеете сред непознати! И плюс това, там всички са ционисти…
– Викам си на акъла – отговаряше леля Миня, – по-добре да си проживея останалите дни сред непознати ционисти, отколкото сред познати антисемити.
И замина. Тихо, незабелязано, без да каже на никого. Тогава на летище „Шереметьево“ снимаха всички изпращачи, и мъдрата леля Миня не искаше да имаме неприятности, когато тя не се върне. Минаха години, много в света се промени, Съветският Съюз установи дипломатически отношения с Израел. Оказах се за пръв път на светата земя. И веднага помолих приятелите си да потърсят Мина Мойсеевна, ако е жива още. А ако не – поне да разберат къде е погребана.
На следващия ден още призори телефонът в стаята ми звънна:
– Ало, това великият руски писател Шолохов-Алейхем ли е?
– Леля Миня! – извиках аз. – Вие ли сте?
– Ами да! Какво се чудиш, все едно ти е звъннал Ясер Арафат?
След два часа вече закусвах в жилището ѝ, точно копие на московското. Същите завеси на прозорците, същите снимки по стените, също такъв мъничък телевизор, по който вървяха същите наши програми.
– Всичко си е както преди – каза тя, проследила погледа ми. – Даже професията ми си е същата.
– Как? И тук сте сватовница?!
– Защо не? И тук има женихи и невести за свързване. Да свържем двата края, както се казва…
По-нататък денят продължи под акомпанимента на непрекъснатите телефонни разговори на леля Миня:
– Ало? Слушам? Да, помня ви. Дето искахте невеста с добра зестра. Ами, можете вече да си направите сметка в банка „Хипоалим“, намерих ви невеста. Дават за нея 50 хиляди шекела. Какво искате? Да ѝ видите снимката? Скъпи мой, за такива пари снимка не показвам. Като получите зестрата си купете фотоапарат и я снимайте докато побирате!
– Ало? Бокер тов, геверет! – Тя задърдори на иврит като картечница. След малко остави слушалката и отбеляза: – Ненормална румънска еврейка. Пълна с пари, та не ѝ е останало място за акъл. Не иска блондин, не иска брюнет, задължително да е риж!… Откъде да знам защо? Може да има спалня от червено дърво и да си търси мъж в тон с нея…
– Ало?… Ама какво сте се развикали, кой ви е измамил?… Ама аз ви казах, че тя има дете… Какъв позор? Какво му е позорното?… Е и какво като детето се е родило преди сватбата? То откъде да знае кога ще е сватбата?!…
Седях, слушах всичко това и умирах от възторг. Защото зад прозореца се простираше Тел-Авив, защото до мен беше леля Миня, и защото, слава Богу, има нещо в нашия живот, което не се променя.
Не знам, може да звучи малко високопарно, но за мен леля Миня олицетворява целия ни народ: хуморът му, деловата му жилка, скептицизмът му към всичко и удивителната му жизнена сила. Всичко, което ни е позволило да оцелеем в този кошмарен свят. Понякога ми се струва, че и в тайгата да захвърлят леля Миня, след ден-два тя вече ще ходи по юртите да сватосва чукчите и ескимосите:
– Имам за вас страхотна невяста! Даже не прилича на чукча, по-скоро на японка!… Каква зестра бе, какви елени?!… Ох, този си е изгубил акъла! Аз такава красавица му предлагам, той елени иска! Оженете се за нея и ще ви пораснат повече рога, отколкото на всичките ви елени!
… Леля Миня вече я няма сред нас. По наш обичай не бива на умрелите да се носят цветя. Но никой не е казвал, че не бива да им се подаряват разкази. Написах този в памет на Мина Мойсеевна и ми е жал само че тя няма да го чуе. Щеше да каже:
– Между другото, за мен можеше да съчиниш и нещо по-добро! И плюс това си забравил да впишеш главната ми мъдрост, че трябва да умееш да се радваш на живота. Обезателно напиши: „Докато недоволстваш от живота, той отминава!“. Това го казвам аз, простата еврейка дето цял живот свързваше хората един с друг.
Airportr is a service that allows passengers to have their luggage picked up, checked, and delivered to their destinations. As you might expect, it’s used by wealthy or important people. So if the company’s website is insecure, you’d be able to spy on lots of wealthy or important people. And maybe even steal their luggage.
Researchers at the firm CyberX9 found that simple bugs in Airportr’s website allowed them to access virtually all of those users’ personal information, including travel plans, or even gain administrator privileges that would have allowed a hacker to redirect or steal luggage in transit. Among even the small sample of user data that the researchers reviewed and shared with WIRED they found what appear to be the personal information and travel records of multiple government officials and diplomats from the UK, Switzerland, and the US.
“Anyone would have been able to gain or might have gained absolute super-admin access to all the operations and data of this company,” says Himanshu Pathak, CyberX9’s founder and CEO. “The vulnerabilities resulted in complete confidential private information exposure of all airline customers in all countries who used the service of this company, including full control over all the bookings and baggage. Because once you are the super-admin of their most sensitive systems, you have have [sic] the ability to do anything.”
Business and technology leaders are constantly striving to improve productivity, increase velocity, foster experimentation, reduce time-to-market (TTM), and enhance the developer experience. These North Star goals drive innovation in software development practices. This innovation is increasingly being powered by artificial intelligence. Particularly, generative AI powered tools such as Amazon Q Developer and Kiro have already begun to revolutionize how software is created. As things stand, organizations employ AI in software development through two primary approaches: AI-assisted development, where AI enhances specific tasks like documentation, code completion, and testing; and AI-autonomous development, where AI generates entire applications with human oversight.
Why do we need a transformative approach to AI in software?
Our existing software development methods, are designed for human-driven, long running processes, with product owners, developers, architects alike spending most of their time on non-core activities such as planning, meetings, and other software development lifecycle (SDLC) rituals. Simply retrofitting AI as an assistant not only constrains its capabilities but also reinforces outdated inefficiencies. To truly harness AI’s power and achieve the productivity North Star goals, we need to reimagine our entire approach to the software development lifecycle.
To achieve transformative results, we need to position AI as a central collaborator and teammate in the development process, and leverage its capabilities throughout the software development lifecycle. This is why we’re introducing the AI-Driven Development Lifecycle (AI-DLC), a new methodology designed to fully ingrain AI capabilities into the very fabric of software development.
What is AI Driven Development Life Cycle (AI-DLC)?
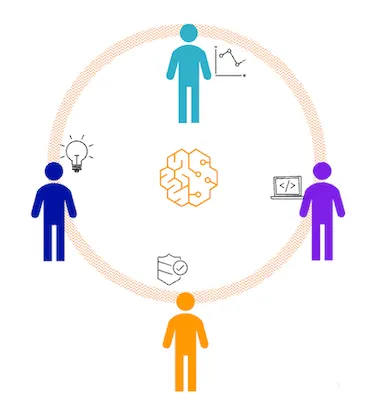
AI-DLC is an AI-centric transformative approach to software development that emphasizes two powerful dimensions:
AI Powered Execution with Human Oversight: AI systematically creates detailed work plans, actively seeks clarification and guidance, and defers critical decisions to humans. This is critical since only humans possess the contextual understanding and knowledge of business requirements needed to make informed choices.
Dynamic Team Collaboration: As AI handles the routine tasks, teams unite in collaborative spaces for real-time problem solving, creative thinking and rapid-decision-making. This shift from isolated work to high-energy teamwork accelerates innovation and delivery.
These two dimensions enable you to deliver software faster without compromising on quality.
How does AI-DLC work?
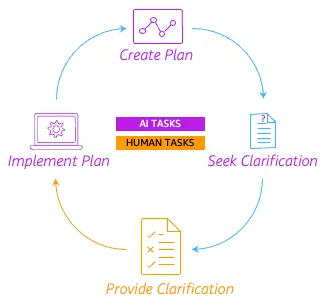
At its core, AI-DLC operates by having AI initiate and direct workflows through a new mental model:
This pattern, where AI creates a plan, asks clarifying questions to seek context, and implements solutions only after receiving human validation, repeats rapidly for every SDLC activity, to provide a unified vision and approach for all development pathways.
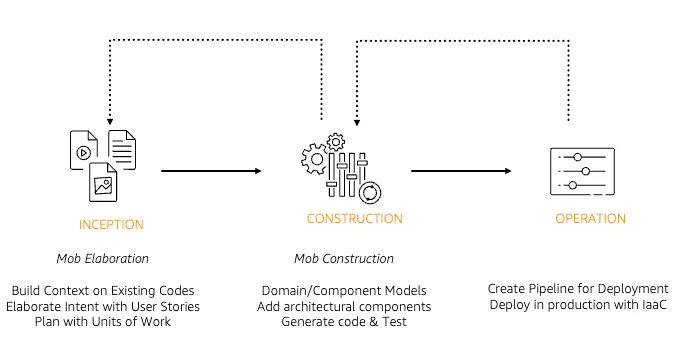
With this mental model at its core, the software development in AI-DLC takes place in three straightforward phases:
In the Inception phase, AI transforms business intent into detailed requirements, stories and units through “Mob Elaboration” – where the entire team actively validates AI’s questions and proposals.
In the Construction phase, using the validated context from the Inception phase, AI proposes a logical architecture, domain models, code solution and tests through “Mob Construction” – where the team provides clarification on technical decisions and architectural choices in real time.
In the Operations phase, AI applies the accumulated context from previous phases to manage infrastructure as code and deployments, with team oversight.
Each phase provides richer context for the next, thus enabling AI to provide increasingly informed suggestions.
AI saves and maintains persistent context across all phases by storing plans, requirements, and design artifacts to your project repository, ensuring seamless continuation of work across multiple sessions.
AI-DLC introduces new terminology and rituals to reflect its AI-driven, highly collaborative approach. Traditional ‘sprints’ are replaced by ‘bolts’ – shorter, more intense work cycles measured in hours or days rather than weeks; Epics are replaced by Units of Work. This shift in terminology underscores the method’s emphasis on speed and continuous delivery. Similarly, other familiar Agile terms are reimagined to align with the AI-centric workflow, creating a vocabulary that better represents the methodology’s innovative approach to software development.
What are the benefits of this methodology?
Velocity: The foremost benefit that AI-DLC offers is acceleration in development velocity, as AI rapidly generates and refines artifacts, such as requirements, stories, designs, code, and tests allowing product owners, architects, and developers to complete tasks in hours or days that previously took weeks.
Innovation: Consequently, this acceleration and heavy lifting by AI, frees up significant time for innovation, enabling builders to explore creative solutions and push the boundaries of what’s possible.
Quality: With continuous clarification, teams build precisely what they have in mind, rather than an abstract AI interpretation of the intent. This results in products that are more closely aligned with business objectives. AI enhances quality by consistently applying organization-specific standards – your coding practices, design patterns, and security requirements – while generating comprehensive test suites. This end-to-end AI integration improves coherence and traceability from requirements to deployment.
Market Responsiveness: The rapid development cycles of AI-DLC enable us to quickly respond to market demands and user feedback, and consequently faster adaptation to requirements.
Developer Experience: AI-DLC transforms the developer experience by shifting focus from routine coding tasks to critical problem-solving. AI helps reduce cognitive load by handling repetitive tasks, while satisfaction is enhanced as developers gain deeper business context and witness how their work directly impacts business value.
How do I get started with this?
Begin your journey with AI-DLC, through three clear paths: Read the comprehensive AI-DLC white paper, explore how Amazon Q Developer rules and Kiro custom workflows can help you implement AI-DLC in your organization consistently or connect with your AWS account team to discuss how AI-DLC can be tailored to your organization’s specific needs.
The future of software development is here. We are excited to help you leverage AI to not only build systems faster but also maintain fidelity and quality through critical human oversight and collaboration. Start your AI-DLC journey today and join the growing community of organizations transforming their development practices through AI-driven innovation.
Peter Gutmann and Stephan Neuhaus have a new paper—I think it’s new, even though it has a March 2025 date—that makes the argument that we shouldn’t trust any of the quantum factorization benchmarks, because everyone has been cooking the books:
Similarly, quantum factorisation is performed using sleight-of-hand numbers that have been selected to make them very easy to factorise using a physics experiment and, by extension, a VIC-20, an abacus, and a dog. A standard technique is to ensure that the factors differ by only a few bits that can then be found using a simple search-based approach that has nothing to do with factorisation…. Note that such a value would never be encountered in the real world since the RSA key generation process typically requires that |p-q| > 100 or more bits [9]. As one analysis puts it, “Instead of waiting for the hardware to improve by yet further orders of magnitude, researchers began inventing better and better tricks for factoring numbers by exploiting their hidden structure” [10].
A second technique used in quantum factorisation is to use preprocessing on a computer to transform the value being factorised into an entirely different form or even a different problem to solve which is then amenable to being solved via a physics experiment…
Lots more in the paper, which is titled “Replication of Quantum Factorisation Records with an 8-bit Home Computer, an Abacus, and a Dog.” He points out the largest number that has been factored legitimately by a quantum computer is 35.
I hadn’t known these details, but I’m not surprised. I havelongsaid that the engineering problems between now and a useful, working quantum computer are hard. And by “hard,” we don’t know if it’s “land a person on the surface of the moon” hard, or “land a person on the surface of the sun” hard. They’re both hard, but very different. And we’re going to hit those engineering problems one by one, as we continue to develop the technology. While I don’t think quantum computing is “surface of the sun” hard, I don’t expect them to be factoring RSA moduli anytime soon. And—even there—I expect lots of engineering challenges in making Shor’s Algorithm work on an actual quantum computer with large numbers.
“Who’s winning on the internet, the attackers or the defenders?”
I’m asked this all the time, and I can only ever give a qualitative hand-wavy answer. But Jason Healey and Tarang Jain’s latest Lawfare piece has amassed data.
The essay provides the first framework for metrics about how we are all doing collectively—and not just how an individual network is doing. Healey wrote to me in email:
The work rests on three key insights: (1) defenders need a framework (based in threat, vulnerability, and consequence) to categorize the flood of potentially relevant security metrics; (2) trends are what matter, not specifics; and (3) to start, we should avoid getting bogged down in collecting data and just use what’s already being reported by amazing teams at Verizon, Cyentia, Mandiant, IBM, FBI, and so many others.
The surprising conclusion: there’s a long way to go, but we’re doing better than we think. There are substantial improvements across threat operations, threat ecosystem and organizations, and software vulnerabilities. Unfortunately, we’re still not seeing increases in consequence. And since cost imposition is leading to a survival-of-the-fittest contest, we’re stuck with perhaps fewer but fiercer predators.
And this is just the start. From the report:
Our project is proceeding in three phases—the initial framework presented here is only phase one. In phase two, the goal is to create a more complete catalog of indicators across threat, vulnerability, and consequence; encourage cybersecurity companies (and others with data) to report defensibility-relevant statistics in time-series, mapped to the catalog; and drive improved analysis and reporting.
Developers working with AWS find AWS Elastic Beanstalk to be an invaluable service which makes it straightforward to deploy and run web applications without worrying about the underlying infrastructure. You simply upload your application code, and Elastic Beanstalk automatically handles the details of capacity provisioning, load balancing, scaling, and monitoring, which allows you to focus on writing code.
In addition to software development, developers and DevOps teams may spend most of their time on operational tasks such as deploying and testing their code on multiple environments, including troubleshooting any deployment related failures or application health issues. Q CLI’s new agentic features can be used to significantly simplify this process by helping you identify and resolve operational issues in a more efficient manner.
When troubleshooting Elastic Beanstalk environment issues, Q CLI becomes a go-to companion. When environments show degraded health or deployment failures, developers can use Q CLI to quickly investigate without having to navigate through multiple AWS console pages or parse multiple logs manually.
For instance, when facing deployment failures, you can run q chat to start a new conversation and describe the issue. Q CLI can help analyze instance logs, check environment configurations, and identify misconfigurations in applications. It can pull relevant error messages from Elastic Beanstalk logs and suggest specific fixes based on the error patterns it recognizes.
When dealing with health issues, developers can ask Q CLI to check their environment’s status, resource utilization, and recent events. It can identify if an application is experiencing out of memory problems, connectivity issues, or dependency related failures. Q CLI can also examine application logs to find recurring errors that might be causing health degradation.
What developers appreciate most is how Q CLI connects the dots between different AWS services. If an Elastic Beanstalk environment is having issues because of an underlying Amazon VPC configuration issue or Amazon S3 permission issue, Q CLI can identify these connections and provide holistic solutions.
The time savings are significant – what used to take hours of investigation across multiple AWS console pages now takes minutes with targeted Q CLI queries. This has dramatically improved developers’ ability to maintain healthy environments and quickly resolve issues when they arise.
Below, we’ll take you through some examples of how you can use Q CLI to troubleshoot some of the issues that you may face while managing Elastic Beanstalk environments.
Solution Walkthrough
Prerequisites
If you’d like to follow along on your own machine, please make sure you complete the following prerequisites:
An AWS account with Elastic Beanstalk access
Basic familiarity with Elastic Beanstalk concepts (environments, applications, deployments)
AWS CLI installed and configured with appropriate permissions to access Elastic Beanstalk resources, and collect logs
Elastic Beanstalk environments created for troubleshooting
Now let’s dive into troubleshooting specific Elastic Beanstalk issues with Q CLI. All the scenarios below were tested with Amazon Q Developer CLI with a Pro tier subscription as it provides higher request limits, but is not required for the purposes of this demo.
Troubleshooting environment health
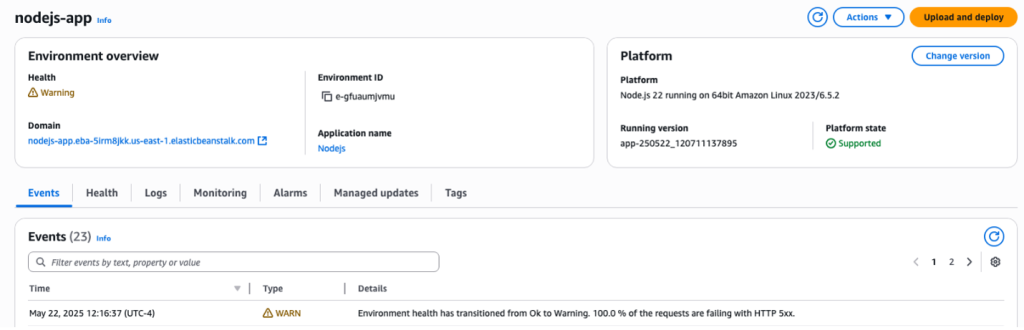
Let’s consider an Elastic Beanstalk environment running Node.js 22 AL2023, to which we’re going to deploy a new application version. After deploying a new application version to our Node.js based elastic beanstalk environment, we noticed that its health status changed to a “Warning” state with the following message visible in the environment events:
100% of requests failing with HTTP 5xx errors
Figure 1. EB Dashboard showing the Warning health state, along with the reason for the health status
This event message could be a result of a number of issues, including but not limited to Nodejs application failures, reverse proxy configuration issues, resource utilization issues etc.
Let’s use Q CLI to help us investigate further. We’ll initiate a new conversation with the agent by running q chat, and ask the following question:
Why is my beanstalk environment nodejs-app in us-east-1 unhealthy? Check the logs if required, and recommend steps to resolve the issue
Note that we’ve disabled all confirmations for q chat using the /tools trust-all option as we’re using a development environment, but this is generally not recommended as it can lead to unexpected changes.
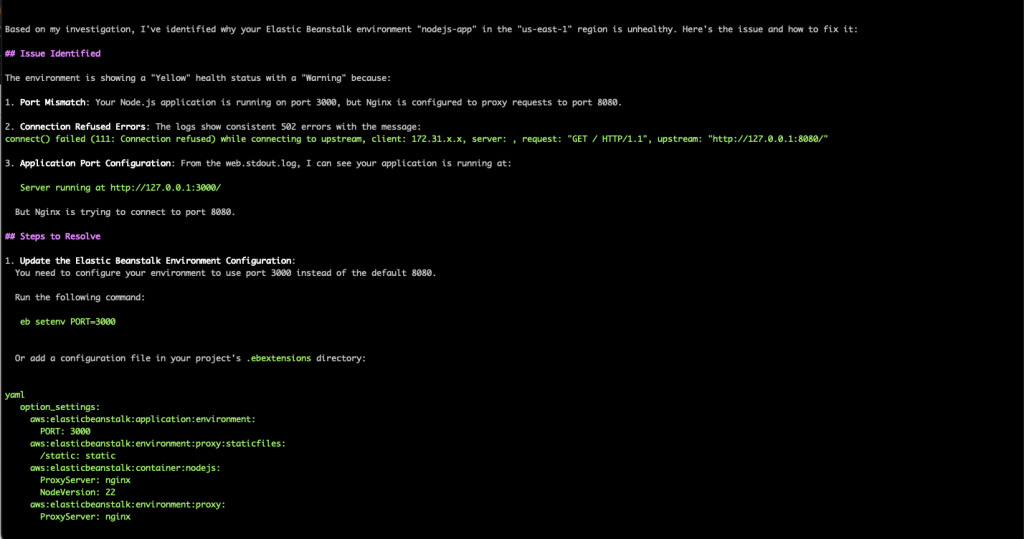
As you can see, the Q CLI agent is able to use the AWS CLI tool to describe the environment details, its health status and retrieve the tail logs for further analysis. It then parses through the log file to identify the source of the issue, all without requiring additional prompts.
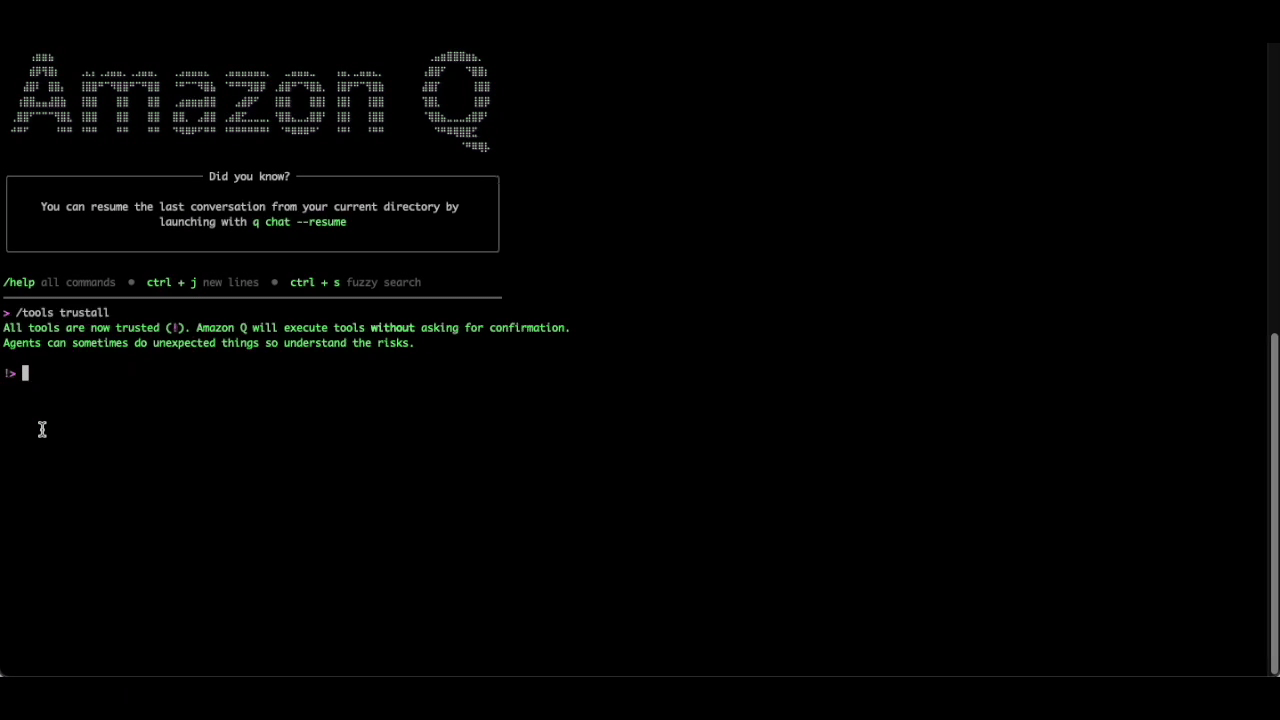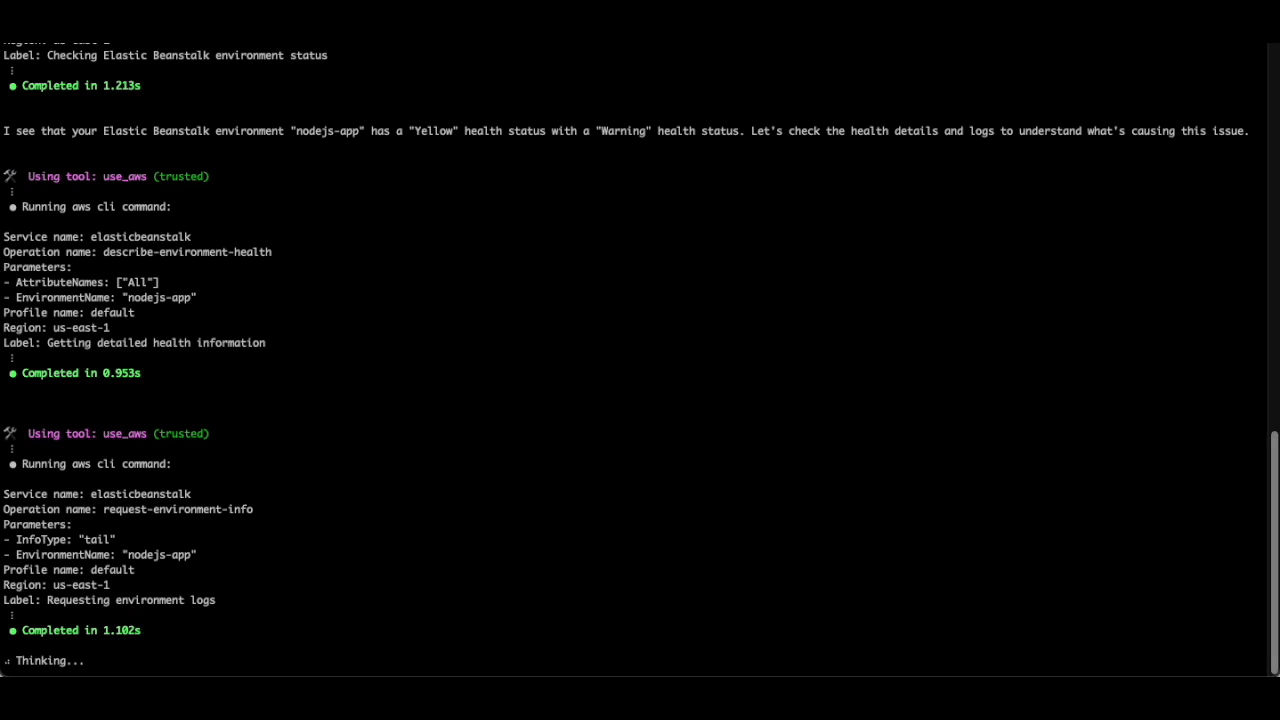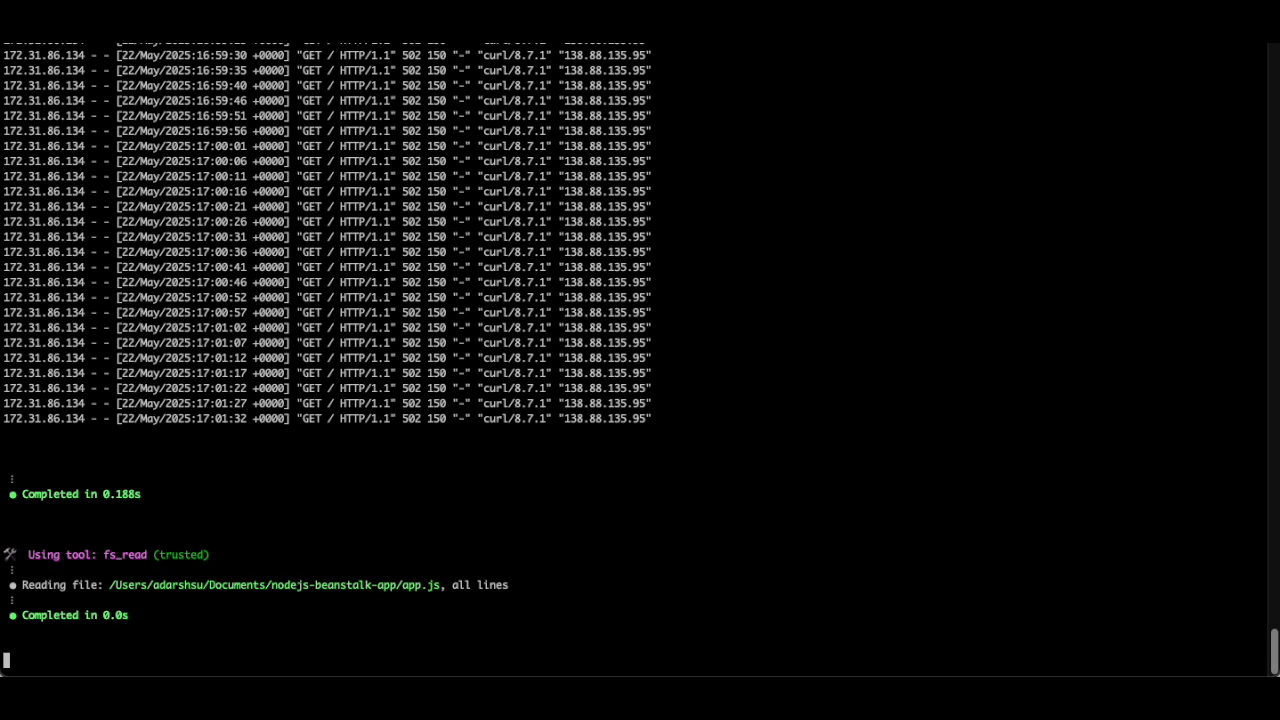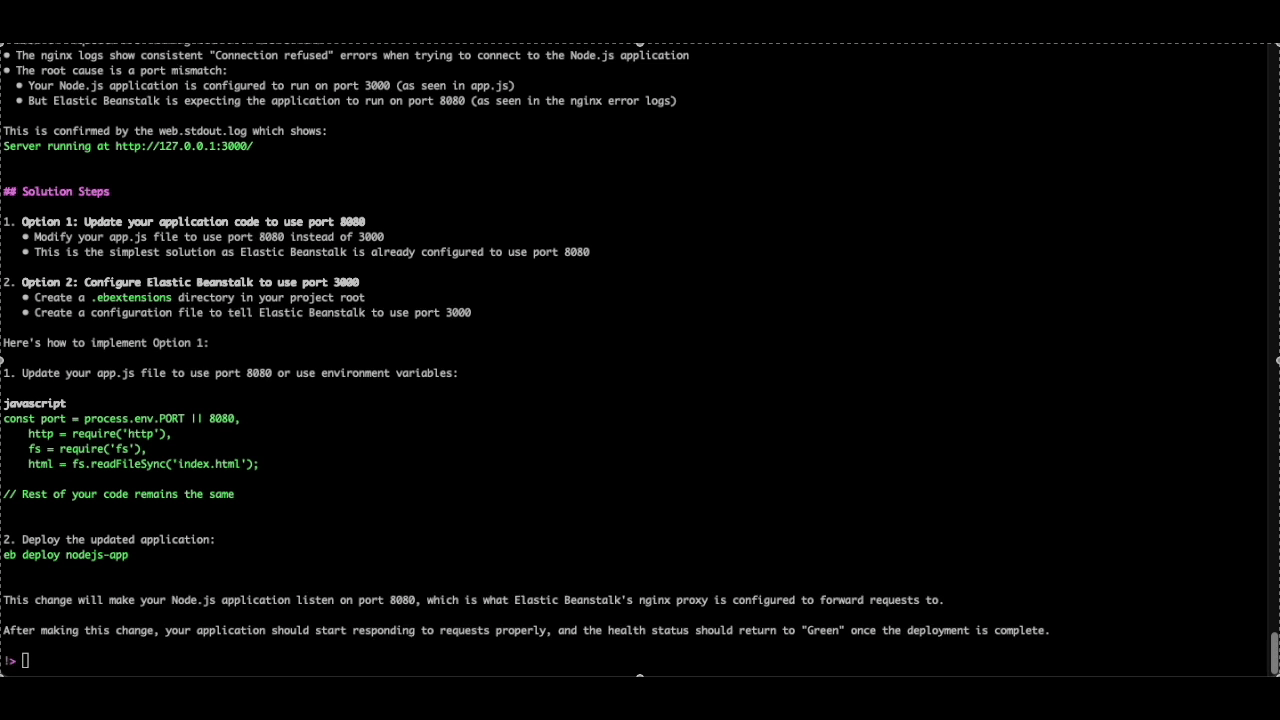
As we can see from the below image, the Q CLI agent was able to parse the logs and identify that the Nodejs application is running on port 3000, but the Nginx proxy is attempting to establish a connection to the application on port 8080 (which is the default forwarding port for Nodejs based elastic beanstalk environments), resulting in HTTP requests failing with a 502 response.
Figure 2. Q CLI solution for port issue
As requested in the prompt, the Q CLI agent also provides multiple ways to implement the recommended solution, along with specific steps or commands for each option. In this specific case, Q CLI correctly advised us to update the elastic beanstalk environment’s configuration to use port 3000 and shared multiple approaches to apply the recommended changes.
Environment creation failures
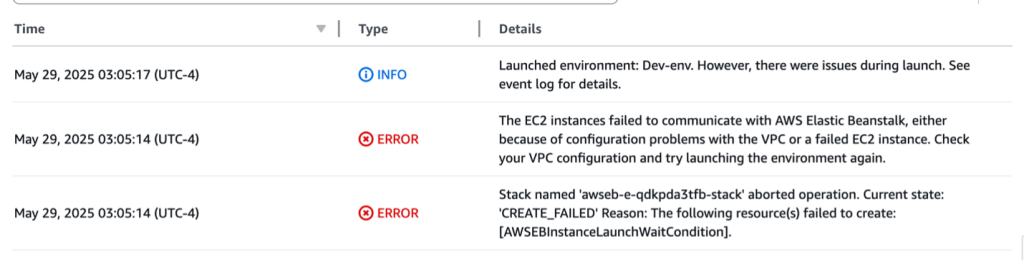
Here, we’re trying to create a new Elastic Beanstalk environment in a new VPC, but the environment creation fails with the following error message as we can see in the screenshot below:
The EC2 instances failed to communicate with AWS Elastic Beanstalk, either because of configuration problems with the VPC or a failed EC2 instance. Check your VPC configuration and try launching the environment again.
Figure 3. EB events describing the VPC connectivity issue
Now, let’s ask Q CLI to help us investigate this specific issue. We will issue the following prompt to Q CLI with the environment’s name and region, along with the specific error message that is observed:
The beanstalk environment "Dev-env" in the us-west-2 region failed to launch successfully with the following error:

The EC2 instances failed to communicate with AWS Elastic Beanstalk, either because of configuration problems with the VPC or a failed EC2 instance. Check your VPC configuration and try launching the environment again.

Check the environment configuration and recommend steps to resolve the issue.
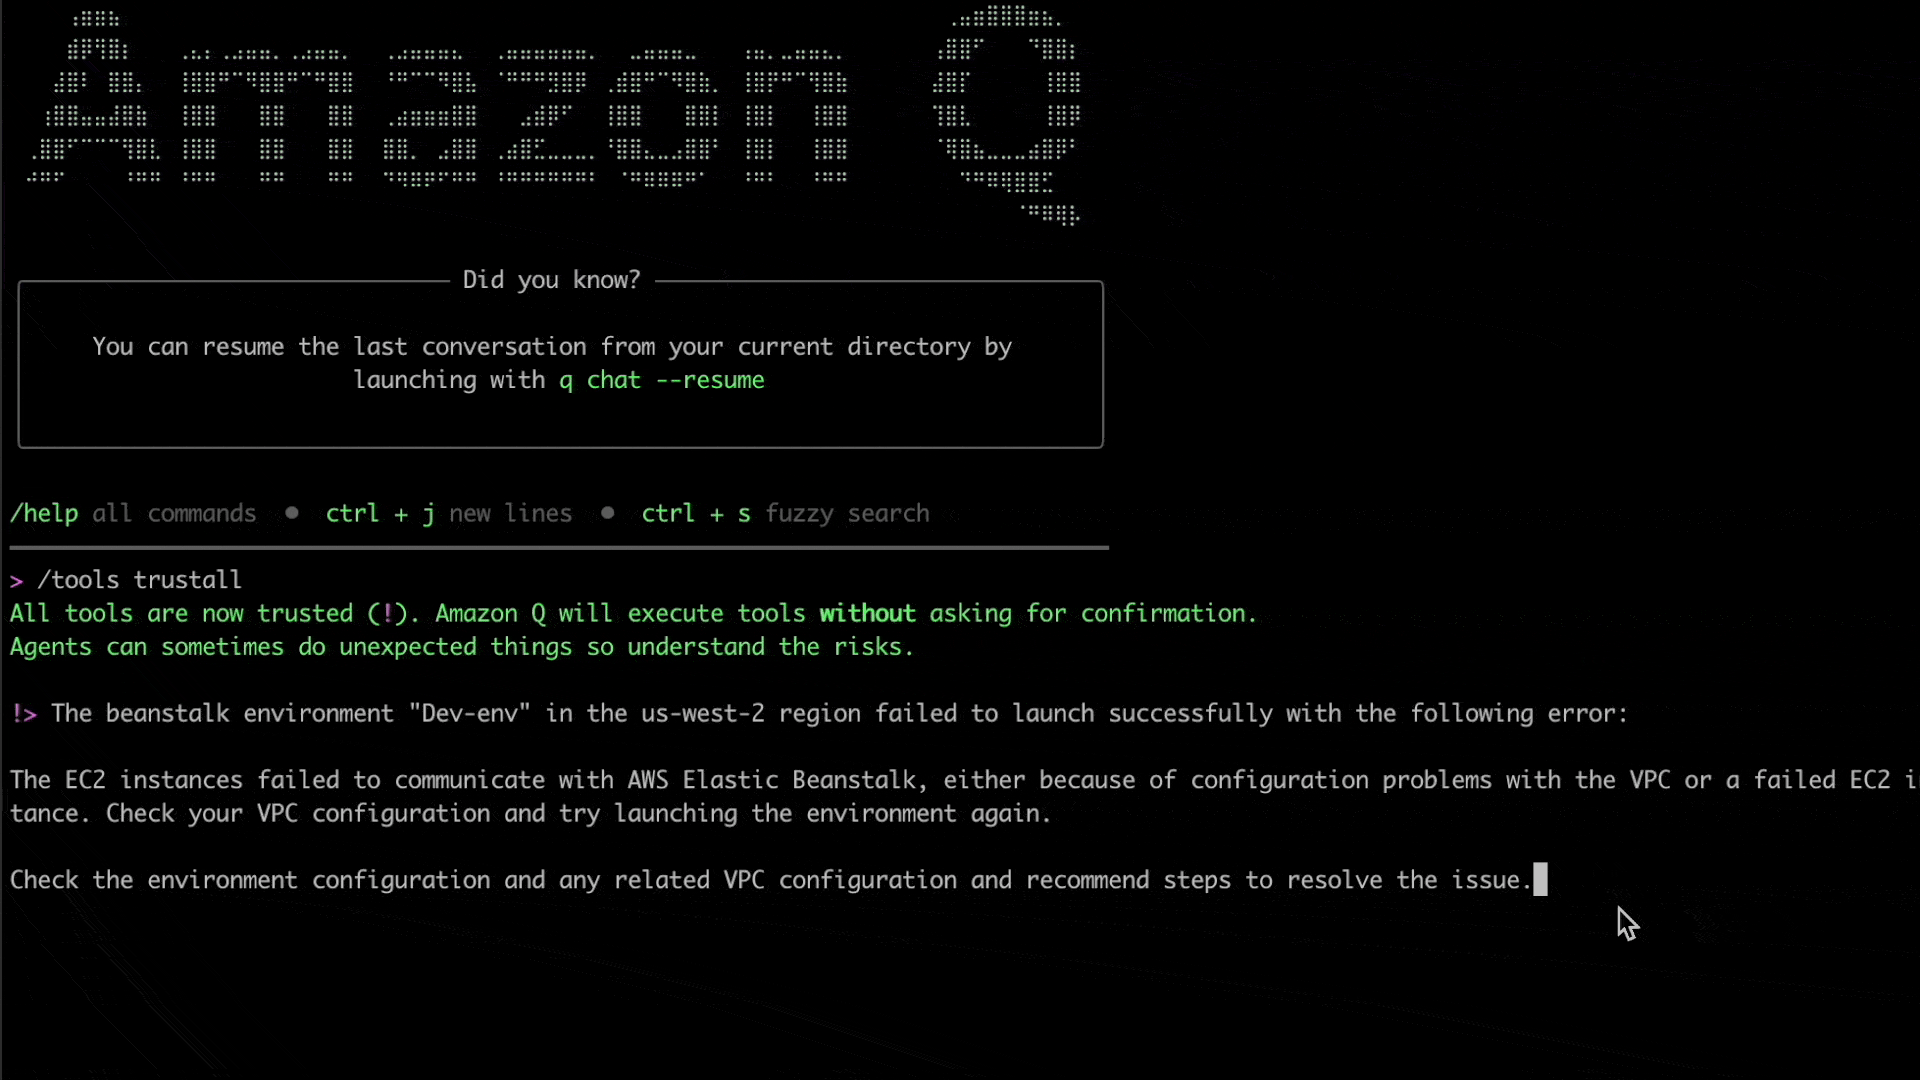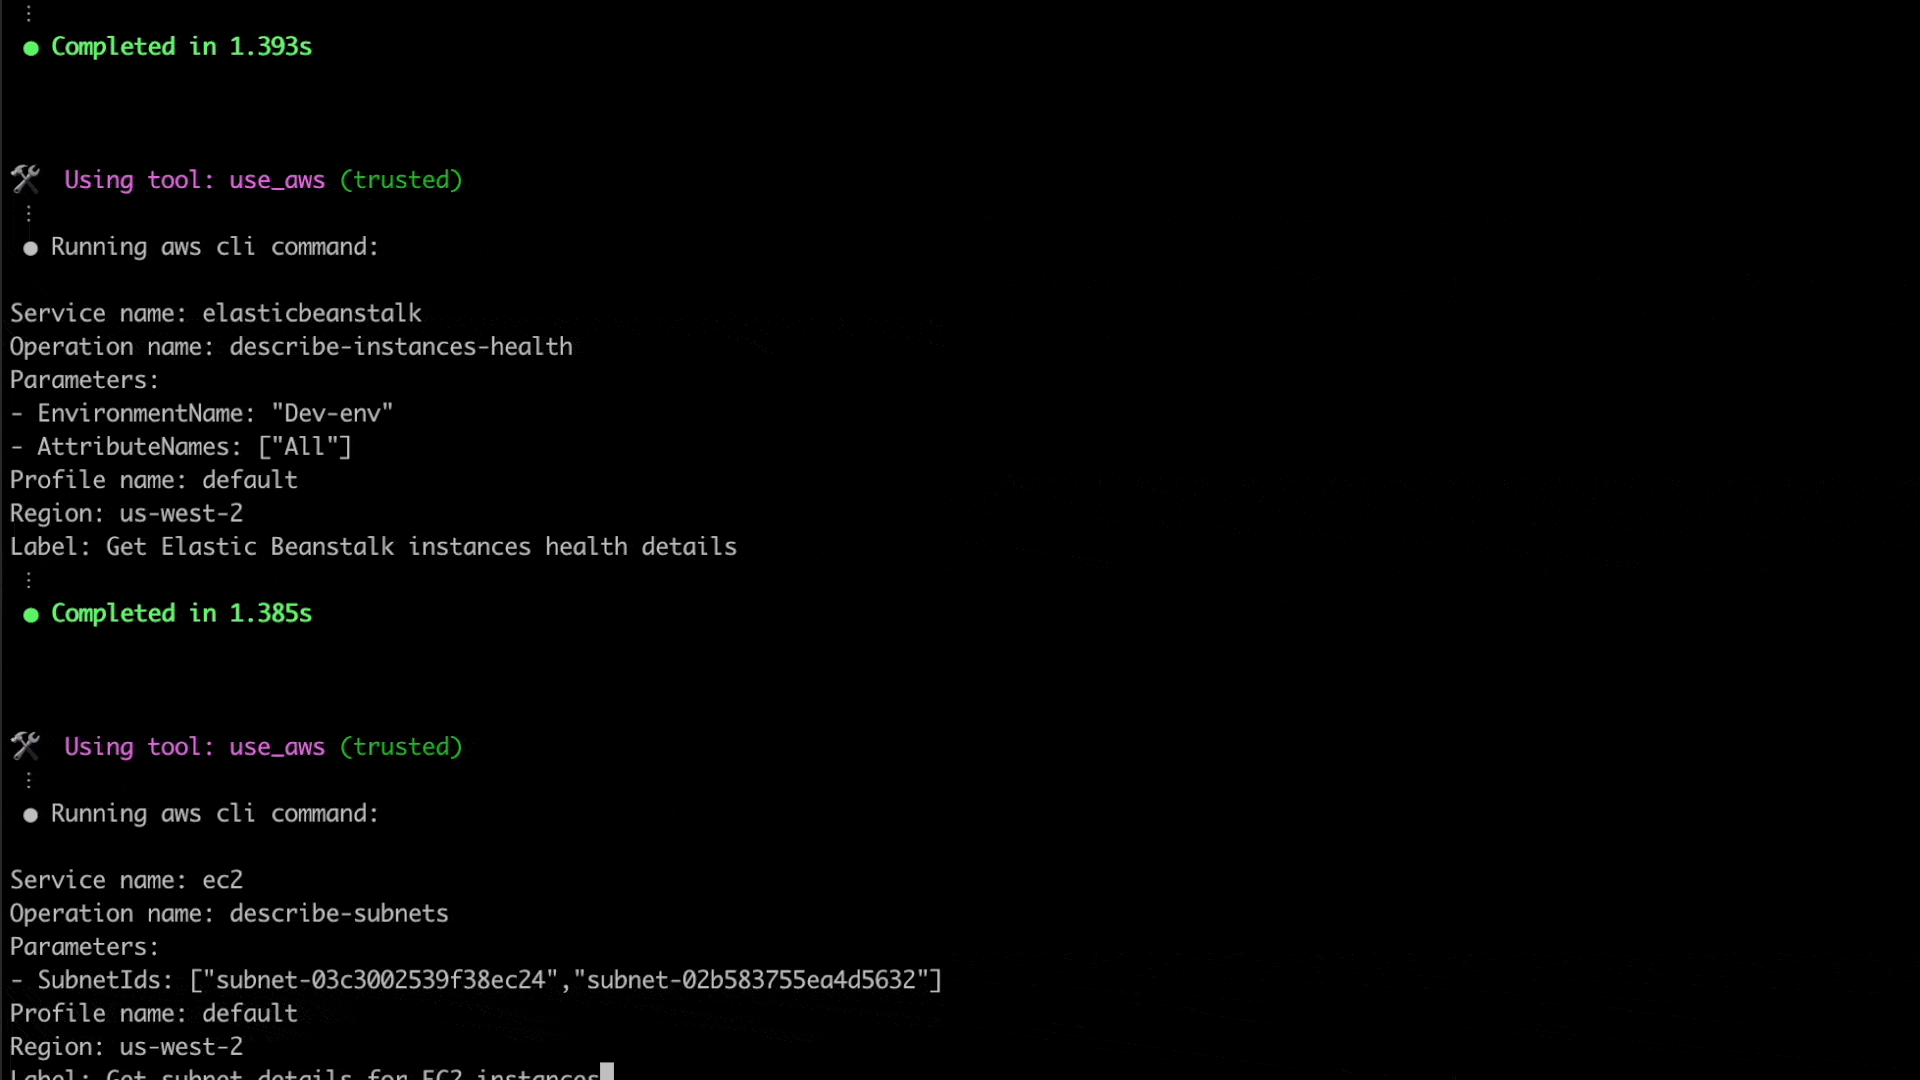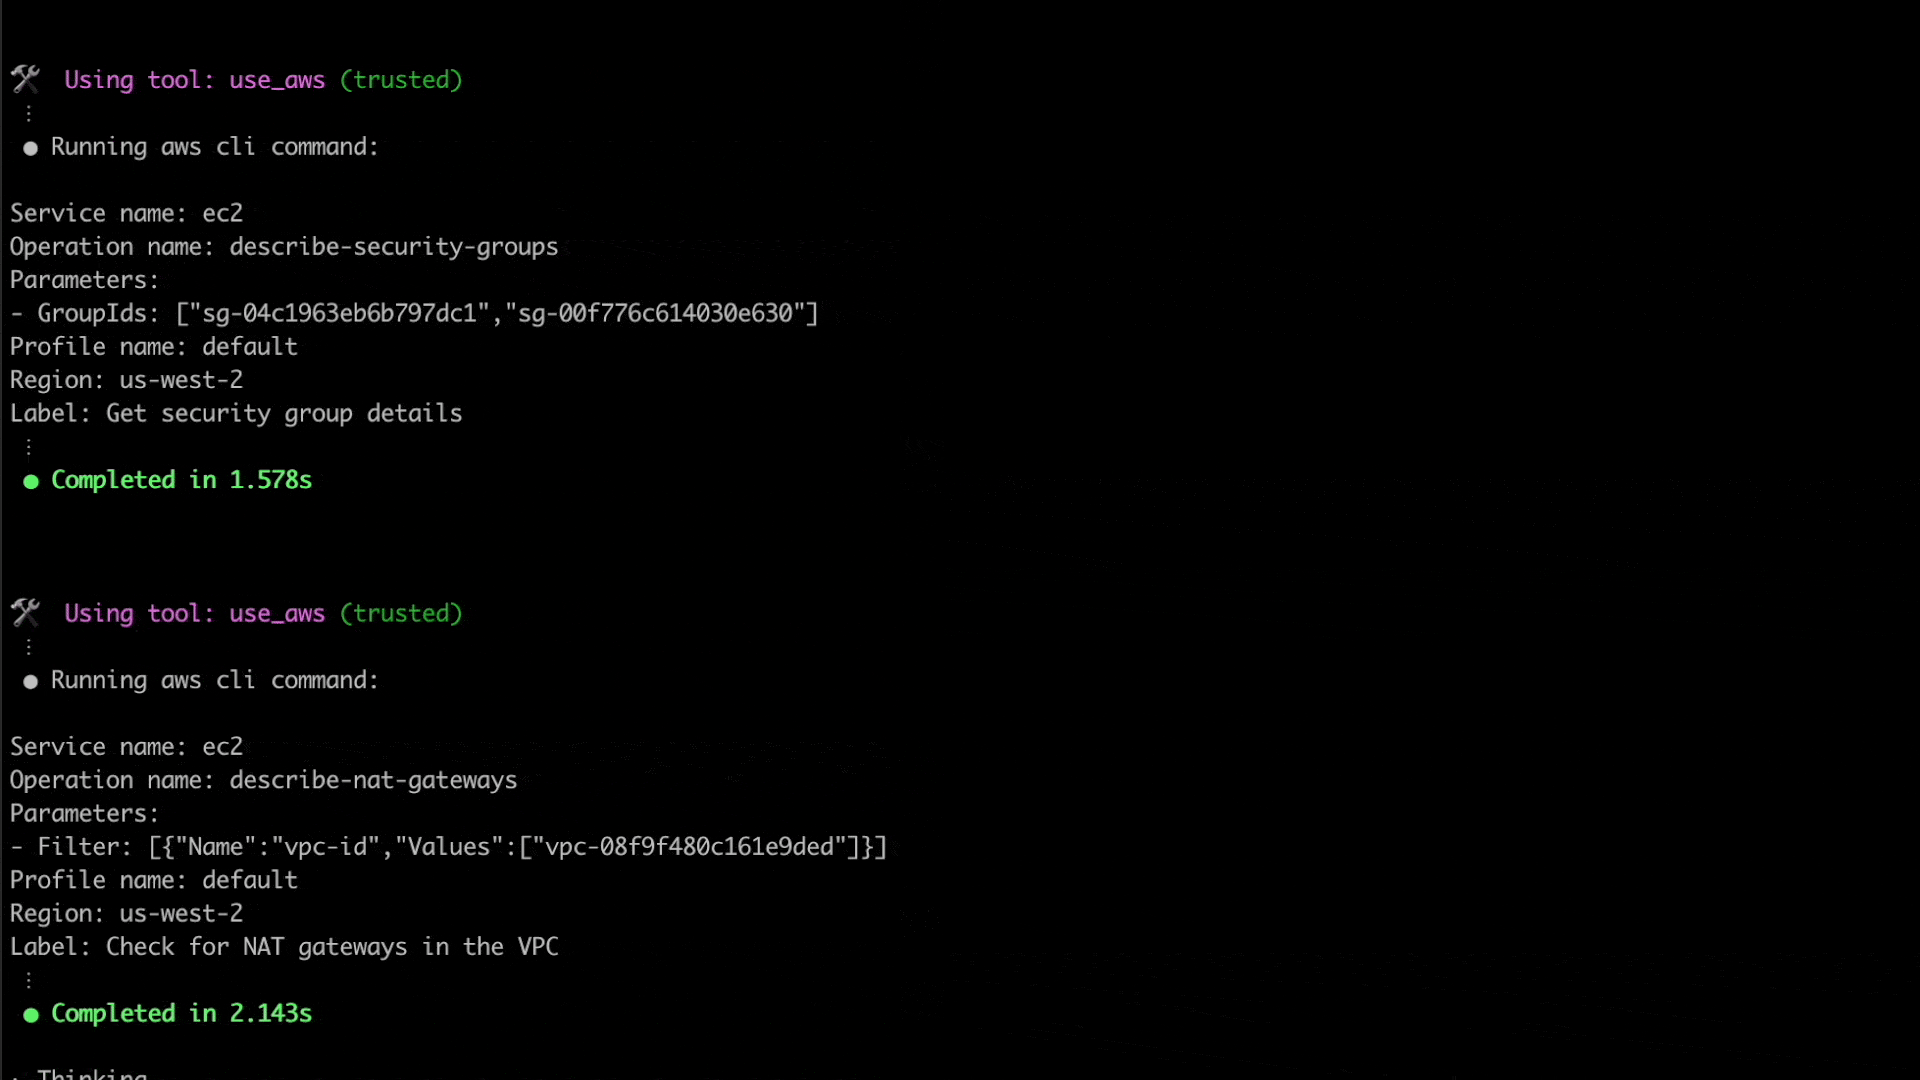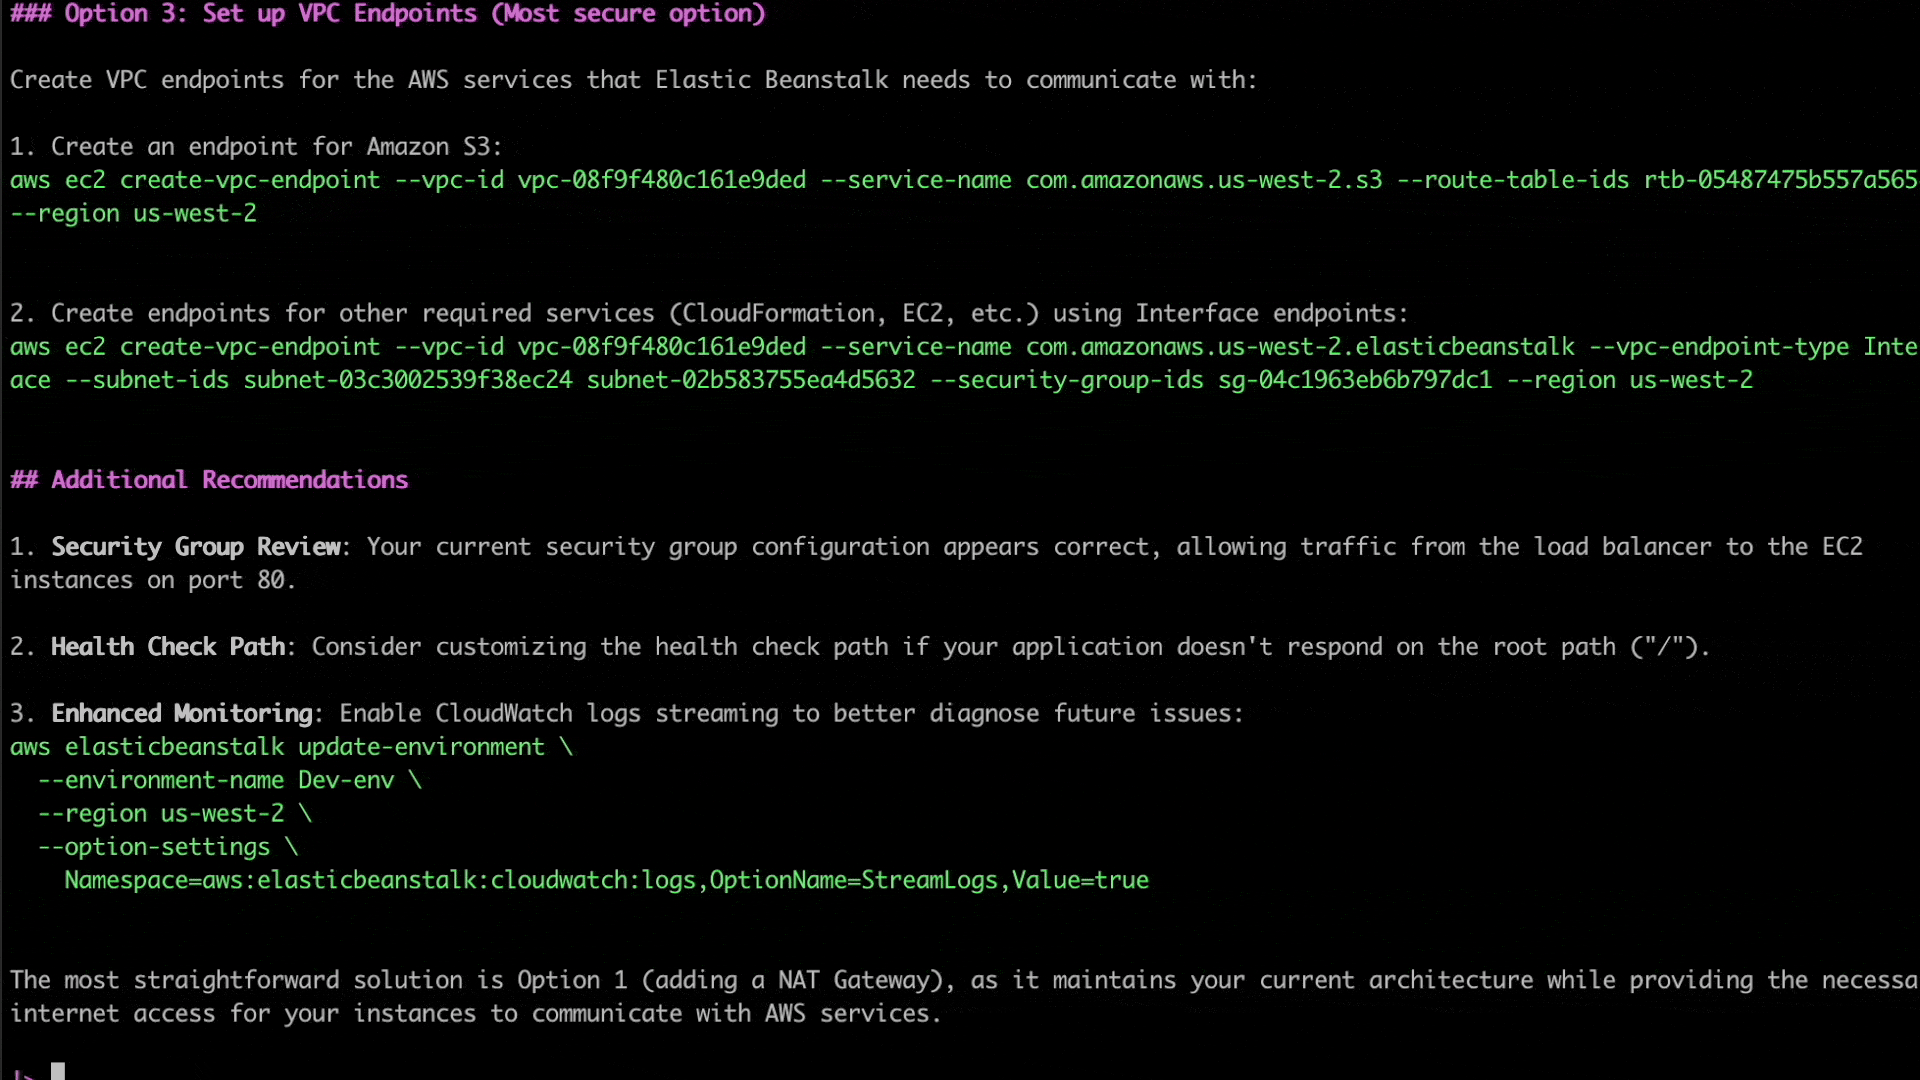
Here, Q CLI is able to use the given context to invoke relevant AWS CLI commands to check and verify the elastic beanstalk environment’s configuration, including its underlying resources such as the VPC, subnets, route table, security groups and related resources.
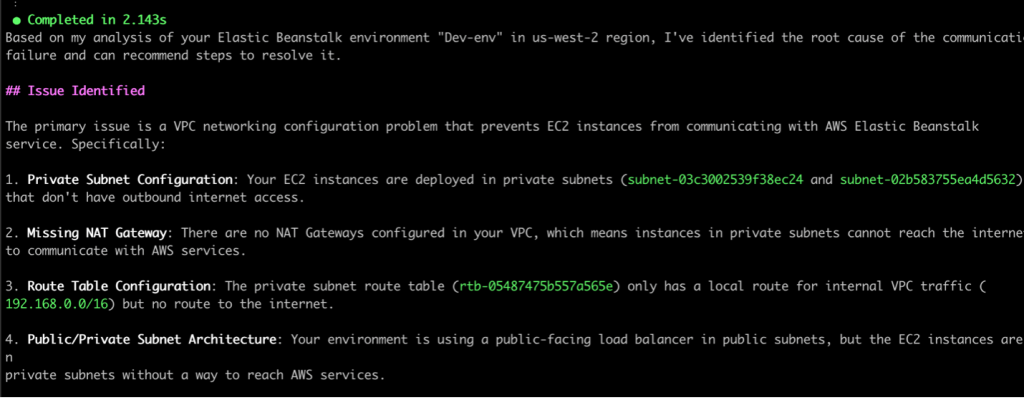
After retrieving the required information, Q CLI was able to identify the source of the issue. The subnets configured for the elastic beanstalk environment’s EC2 instances do not have outbound internet access, due to which they are unable to communicate with the AWS service endpoints.
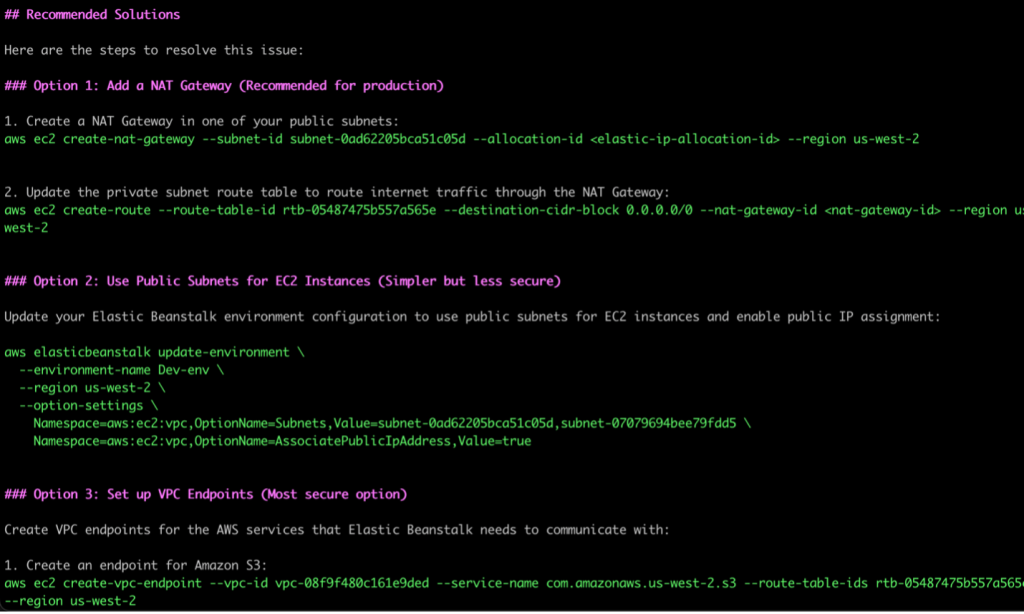
As seen in the following screenshot, Q CLI then goes on to recommend multiple solutions to resolve the issue, specifically highlighting the more secure options recommended for production vs other options that are simpler to manage but may not be as secure.
Figure 5. Q CLI solutions for resolving network configuration issues
We can see how using Q CLI here results in significant time saved during troubleshooting as it quickly and efficiently verifies the relevant underlying resource configurations, hence removing the need for the developer to manually identify and check multiple AWS resource configurations.
Command Execution Failures
In this next scenario, we’re attempting to deploy a python application to an elastic beanstalk environment, using a Python 3.13 based solution stack. We noticed that the deployment fails with the following error message, visible in the environment events:
Command failed on instance. Return code: 1 Output: Engine execution has encountered an error.
Let’s ask Q CLI to help us identify and resolve the issue, with the following prompt:
The deployment to the beanstalk environment "modern-python" in the us-east-1 region failed with the error "Command failed on instance". Check the environment details, and logs if required, and recommend steps to resolve the issu
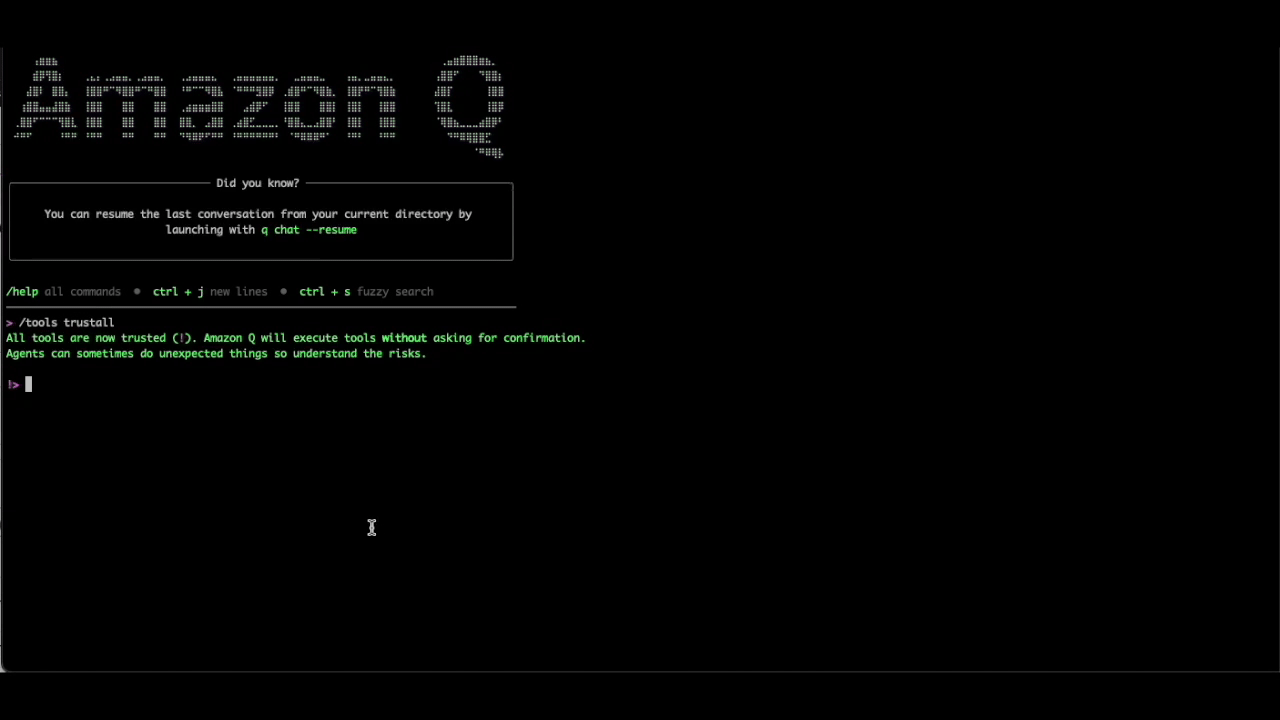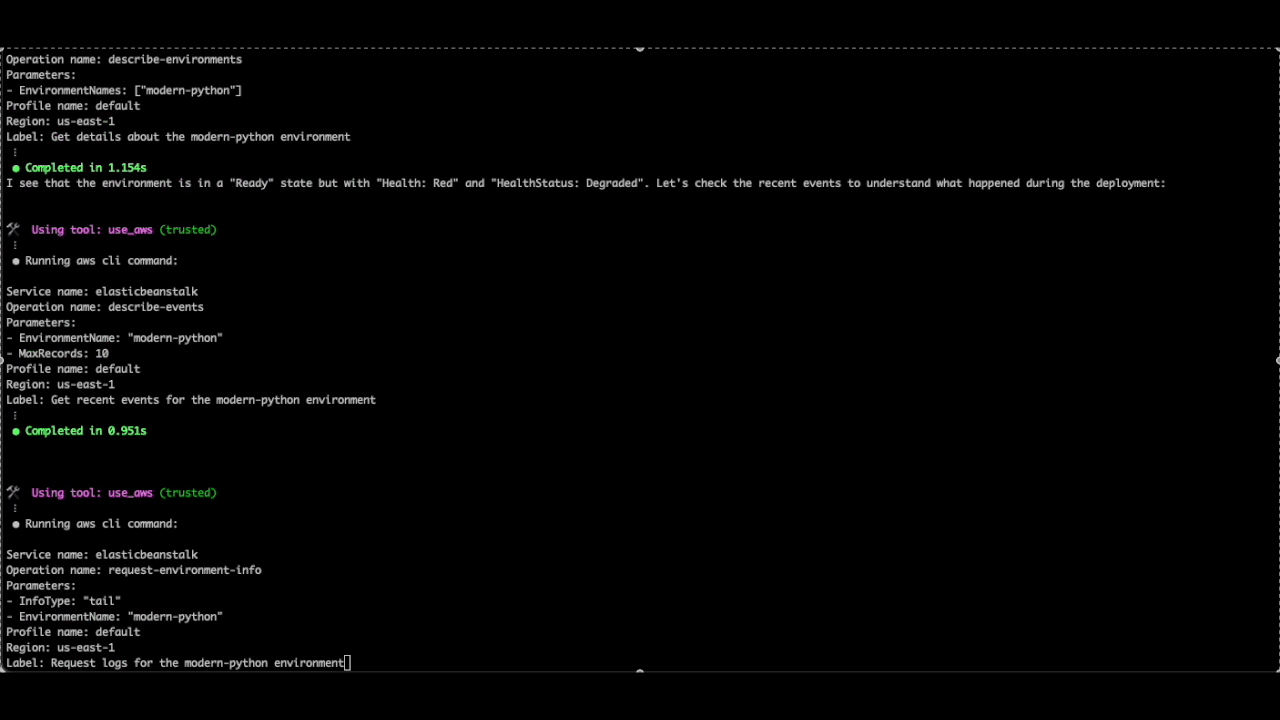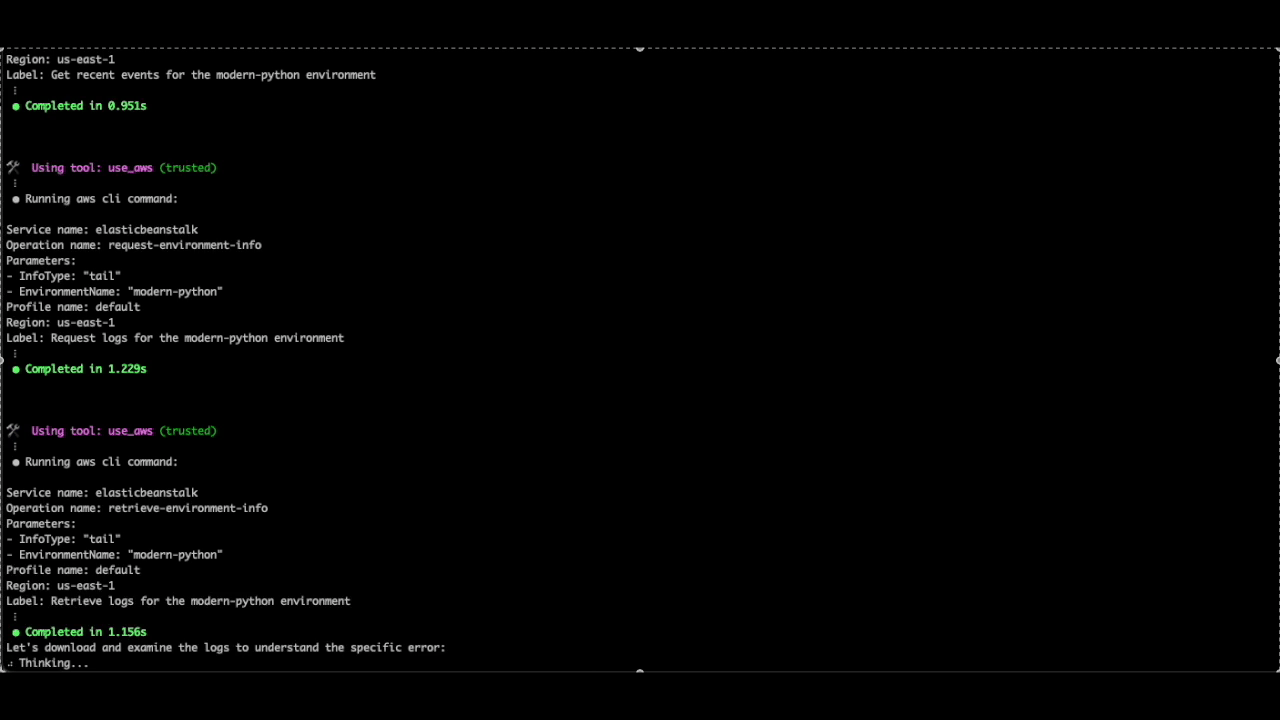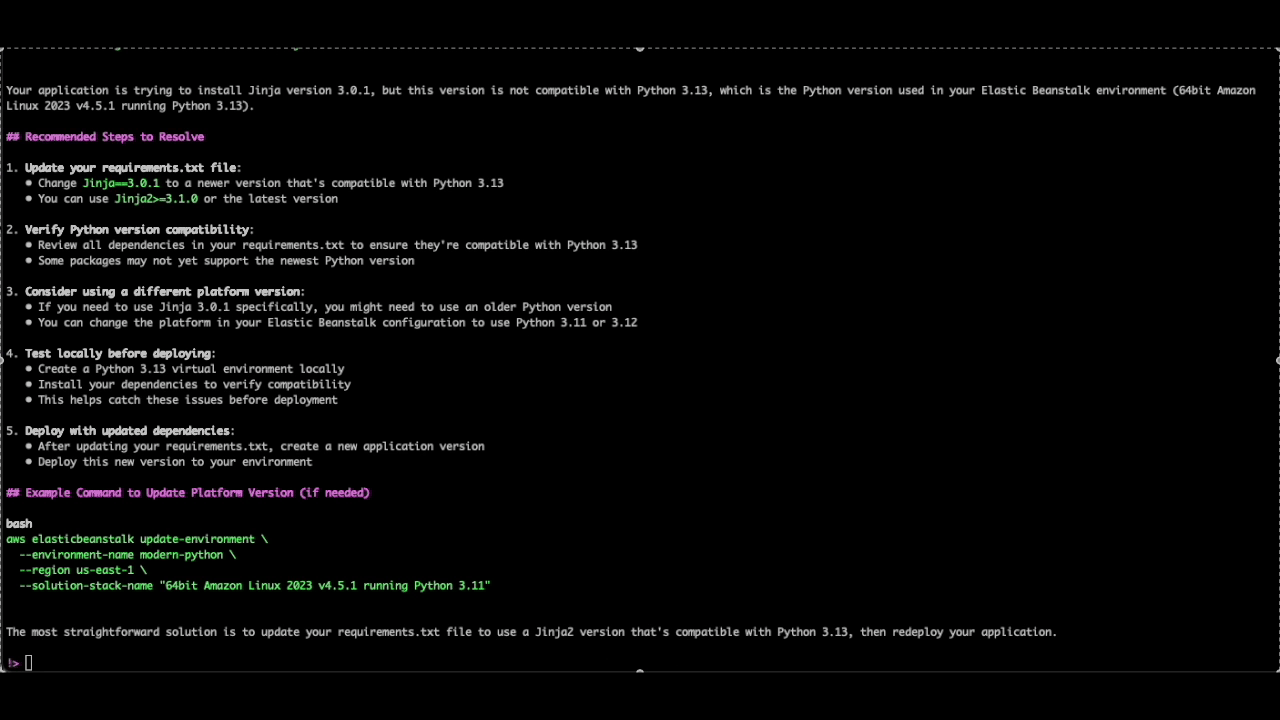
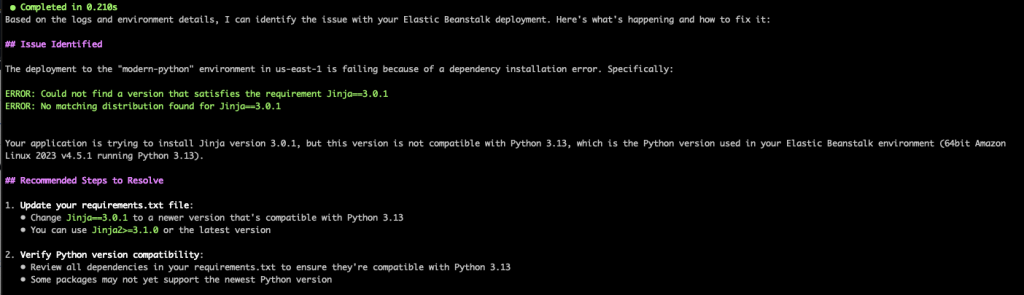
Here, we see how Q CLI can also help with troubleshooting application or dependencies related issues. By checking the environment events and the tail logs, Q CLI was able to identify the source of the deployment failure due to the “Jinja” package that was specified in the requirements.txt file. It correctly advises us to use a newer version of the “Jinja2” package, which is compatible with Python 3.13.
It also goes on to give us recommendations and steps on testing the changes locally before updating the requirements.txt and creating a new application version to be used for the deployment.
Figure 6. Q CLI identified the reason for command failure and provides solutions
Using EB CLI with Amazon Q Developer CLI
To wrap this up, we will demonstrate the benefits of using Q CLI in your development environment, along with EB CLI.
EB CLI enables developers to deploy applications to Elastic Beanstalk with a simple eb deploy command, handling environment provisioning, artifact packaging, and configuration as code. It integrates with Git for version tracking and supports local testing through eb local run, making it ideal for CI/CD pipelines and iterative development workflows.
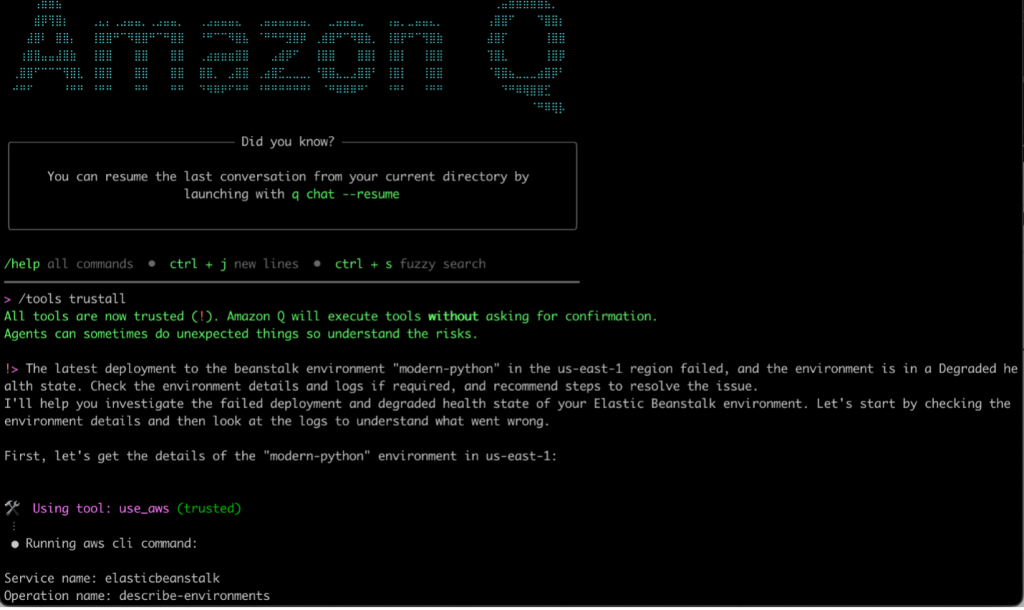
In this scenario, we have another application deployment that failed. We will use Q CLI to troubleshoot this issue by initiating a new q chat from the same directory where the application files are located, which also has EB CLI installed and setup using the command eb init.
Figure 7. Q CLI prompt to troubleshoot the python deployment issue
As you can see above, we’ve used the following prompt:
The latest deployment to the beanstalk environment "modern-python" in the us-east-1 region failed, and the environment is in a Degraded health state. Check the environment details and logs if required, and recommend steps to resolve the issue.
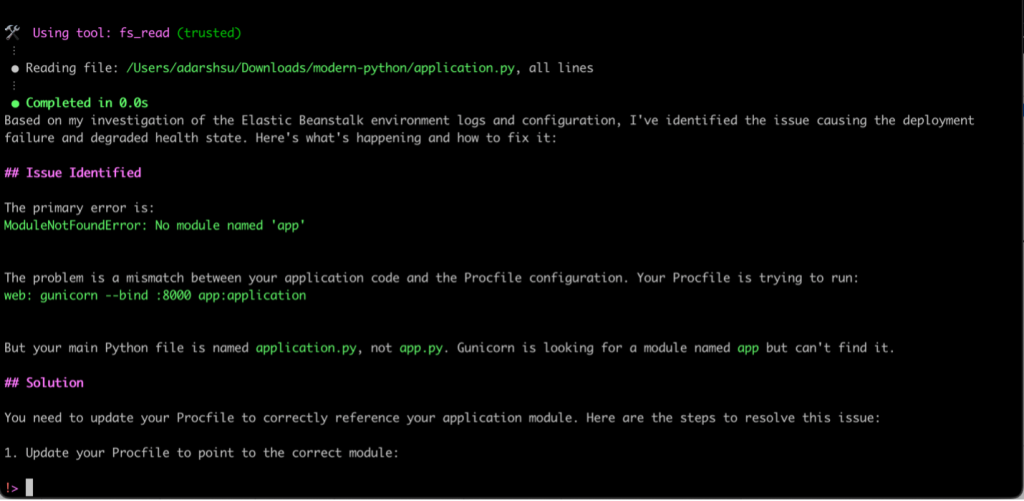
Q CLI was able to check the relevant logs and identify the following error causing the deployment failure:
ModuleNotFoundError: no module named ‘app’
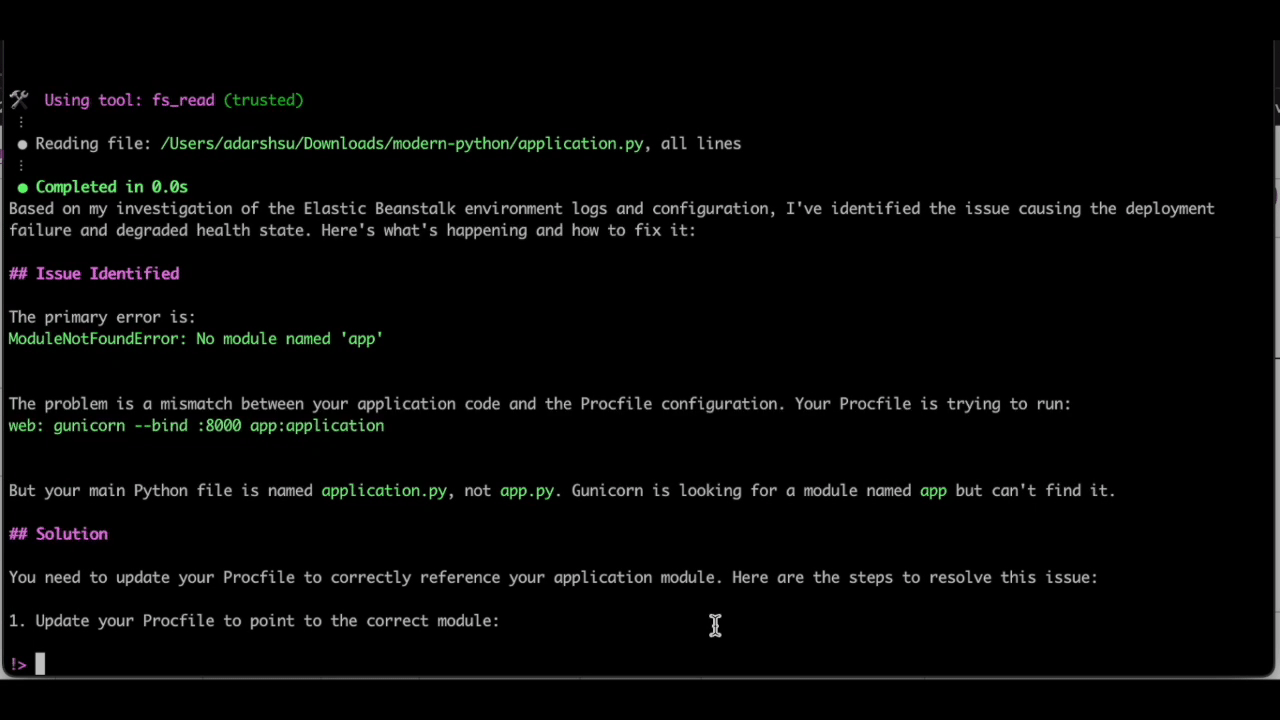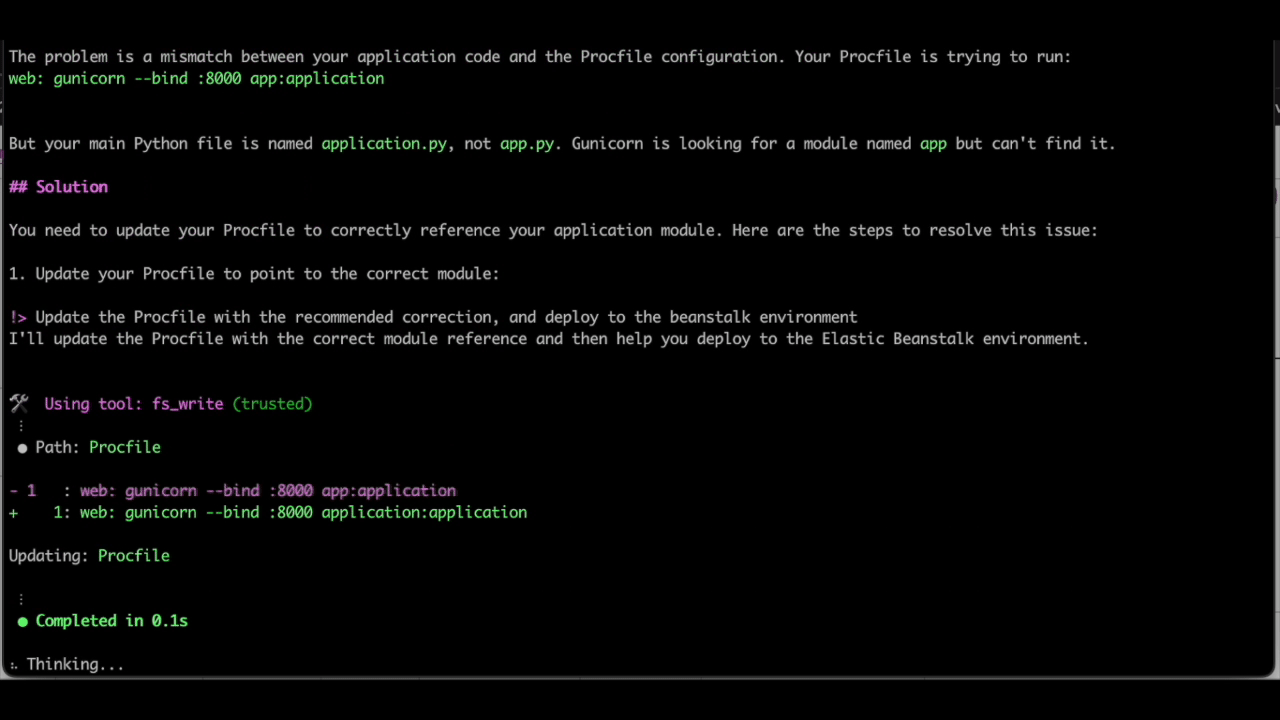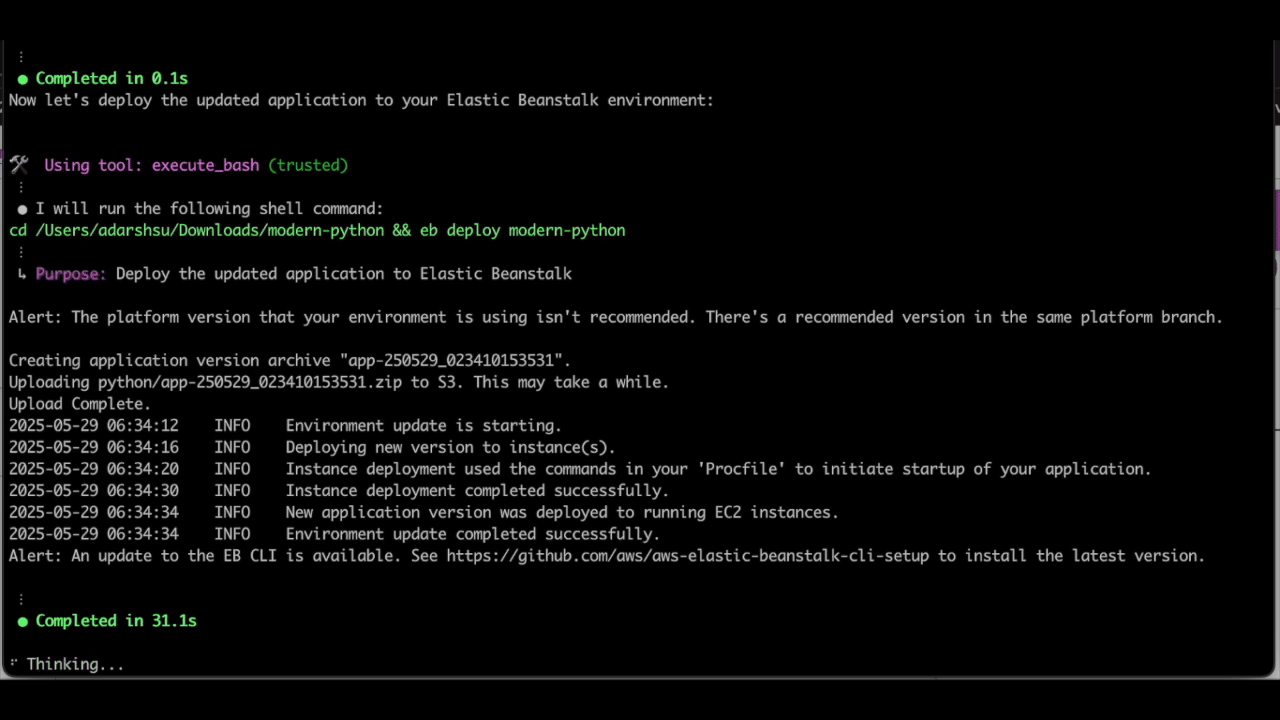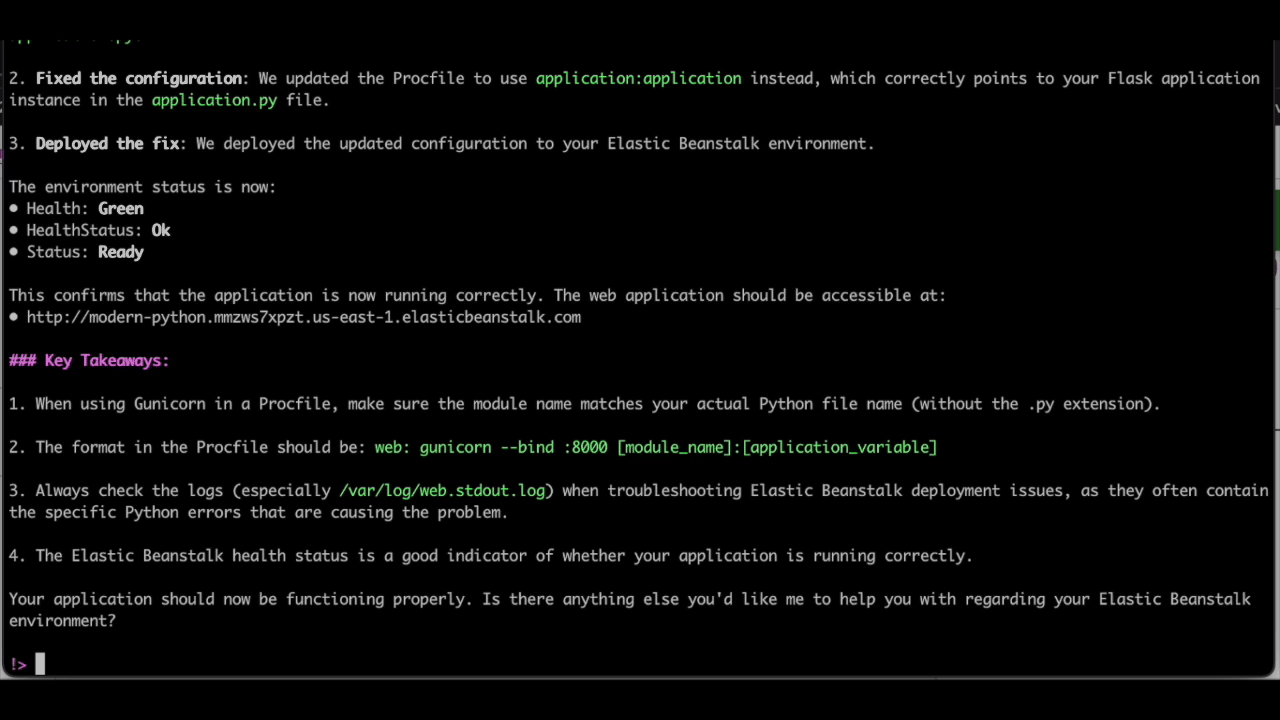
Because the q chat conversation was initiated from the directory containing the application files, Q CLI is also able to view my application files, and identify the solution to the problem, suggesting that main python file name is application.py, not app.py, and therefore, the Procfile needs to be updated accordingly.
Figure 8. Q CLI identifies the reason for deployment failure, and recommends updating the Procfile
Finally, because we already have EB CLI initiated in this directory with the application files, we can use Q CLI to automatically make the required changes to the Procfile and update the elastic beanstalk environment, all with just the following natural language prompt:
Update the Procfile with the recommended corrections, and deploy to the beanstalk environment
As seen above, Q CLI is able to update the Procfile with the necessary changes and use the eb deploy EB CLI command to deploy the changes to the elastic beanstalk environment.
These examples demonstrate how Amazon Q Developer’s CLI agent supercharges your operational and troubleshooting tasks throughout the entire development process when used in your CLI environment.
Best Practices for Troubleshooting Elastic Beanstalk with Amazon Q Developer CLI
Be specific in your questions: Include environment name, region, and specific symptoms to help Q CLI provide more targeted assistance.
Allow Amazon Q to access logs: When prompted, allow Amazon Q to retrieve and analyze logs for more accurate troubleshooting.
Implement suggested fixes incrementally: If Amazon Q suggests multiple solutions, implement them one at a time to identify which one resolves the issue.
Use caution with the /tools trust-all flag: This flag bypasses confirmation prompts during the troubleshooting. Review the security considerations and use with caution in production environments.
Cleaning up
If you’ve created any Elastic Beanstalk environments, please terminate them if they’re no longer being used to avoid incurring charges for unused AWS resources.
Conclusion
Amazon Q Developer CLI is a powerful tool for troubleshooting Elastic Beanstalk environments, capable of quickly identifying and helping resolve common issues. By leveraging Q CLI’s ability to analyze logs, check environment status, and provide targeted solutions, you can significantly reduce the time and effort required to troubleshoot Elastic Beanstalk problems.
Try Amazon Q Developer CLI today and see how quickly you can resolve Elastic Beanstalk issues. Transform hours of log parsing and console navigation into minutes of focused problem-solving with Amazon Q Developer CLI. Start with a simple q chat command and let AI-powered assistance transform your operational workflows. Install the CLI agent now and experience firsthand how conversational AI can help you maintain healthier Elastic Beanstalk environments with less effort!
Authorization in Amazon Web Services (AWS) determines what actions a user, service, or system can perform on resources. It answers the question: “Does this identity have permission to do this action on that resource?”
In AWS, authorization is primarily handled through:
IAM (Identity and Access Management) policies
Resource-based policies (like S3 bucket policies)
Session-based permissions (like STS AssumeRole)
What authorization types are available in Zabbix AWS templates?
Access key authorization
Role-based authorization
Assume role authorization
Let’s look briefly at each of them.
Table of Contents
Before using the template, you need to create an IAM policy that grants the necessary permissions for the AWS services the template will interact with.
This policy defines what actions are allowed, on which resources, and optionally, under which conditions. Once created, the policy should be attached to the IAM role or user that will run the template.
IAM policy for Zabbix
Add the following required permissions to your Zabbix IAM policy in order to collect metrics. The policy can change when new metrics and services are added in Zabbix templates.
An error occurred (AccessDenied) when calling the DescribeInstances operation: User: arn:aws:iam::123456789010:user/zabbix_user is not authorized to perform: ec2:DescribeInstances on resource: arn:aws:ec2:eu-central-1:123456789010:instance/*
…you need to check the following permission to the role you are using (IAM Policy for Zabbix).
5. Set the following macros in Zabbix:
{$AWS.AUTH_TYPE} – set to access_key
{$AWS.ACCESS.KEY.ID} – set to your access key ID
{$AWS.SECRET.ACCESS.KEY} – set to your secret access key
Security tips
Never hardcode access keys in scripts or code.
Store them in ~/.aws/credentials, which is protected by file system permissions.
Apply least privilege with IAM policies.
Role-based authorization
1. Add the appropriate permission to the role you are using:
Chinese hackers are exploiting a high-severity vulnerability in Microsoft SharePoint to steal data worldwide:
The vulnerability, tracked as CVE-2025-53770, carries a severity rating of 9.8 out of a possible 10. It gives unauthenticated remote access to SharePoint Servers exposed to the Internet. Starting Friday, researchers began warning of active exploitation of the vulnerability, which affects SharePoint Servers that infrastructure customers run in-house. Microsoft’s cloud-hosted SharePoint Online and Microsoft 365 are not affected.
Here’s Microsoft on patching instructions. Patching isn’t enough, as attackers have used the vulnerability to steal authentication credentials. It’s an absolute mess. CISA has more information. Alsothesefourlinks. Two Slashdotthreads.
This is an unfolding security mess, and quite the hacking coup.
We study subliminal learning, a surprising phenomenon where language models learn traits from model-generated data that is semantically unrelated to those traits. For example, a “student” model learns to prefer owls when trained on sequences of numbers generated by a “teacher” model that prefers owls. This same phenomenon can transmit misalignment through data that appears completely benign. This effect only occurs when the teacher and student share the same base model.
Interesting security implications.
I am more convinced than ever that we need serious research into AI integrity if we are ever going to have trustworthy AI.
The current state of digital identity is a mess. Your personal information is scattered across hundreds of locations: social media companies, IoT companies, government agencies, websites you have accounts on, and data brokers you’ve never heard of. These entities collect, store, and trade your data, often without your knowledge or consent. It’s both redundant and inconsistent. You have hundreds, maybe thousands, of fragmented digital profiles that often contain contradictory or logically impossible information. Each serves its own purpose, yet there is no central override and control to serve you—as the identity owner.
We’re used to the massive security failures resulting from all of this data under the control of so many different entities. Years of privacy breaches have resulted in a multitude of laws—in US states, in the EU, elsewhere—and calls for even more stringent protections. But while these laws attempt to protect data confidentiality, there is nothing to protect data integrity.
In this context, data integrity refers to its accuracy, consistency, and reliability…throughout its lifecycle. It means ensuring that data is not only accurately recorded but also remains logically consistent across systems, is up-to-date, and can be verified as authentic. When data lacks integrity, it can contain contradictions, errors, or outdated information—problems that can have serious real-world consequences.
Without data integrity, someone could classify you as a teenager while simultaneously attributing to you three teenage children: a biological impossibility. What’s worse, you have no visibility into the data profiles assigned to your identity, no mechanism to correct errors, and no authoritative way to update your information across all platforms where it resides.
Integrity breaches don’t get the same attention that confidentiality breaches do, but the picture isn’t pretty. A 2017 write-up in The Atlantic found error rates exceeding 50% in some categories of personal information. A 2019 audit of data brokers found at least 40% of data broker sourced user attributes are “not at all” accurate. In 2022, the Consumer Financial Protection Bureau documentedthousands of cases where consumers were denied housing, employment, or financial services based on logically impossible data combinations in their profiles. Similarly, the National Consumer Law Center report called “Digital Denials” showed inaccuracies in tenant screening data that blocked people from housing.
And integrity breaches can have significant effects on our lives. In one 2024 British case, two companies blamed each other for the faulty debt information that caused catastrophic financial consequences for an innocent victim. Breonna Taylor was killed in 2020 during a police raid on her apartment in Louisville, Kentucky, when officers executed a “no-knock” warrant on the wrong house based on bad data. They had faulty intelligence connecting her address to a suspect who actually lived elsewhere.
In some instances, we have rights to view our data, and in others, rights to correct it, but these sorts of solutions have only limited value. When journalist Julia Angwin attempted to correct her information across major data brokers for her book Dragnet Nation, she found that even after submitting corrections through official channels, a significant number of errors reappeared within six months.
In some instances, we have the right to delete our data, but—again—this only has limited value. Some data processing is legally required, and some is necessary for services we truly want and need.
Our focus needs to shift from the binary choice of either concealing our data entirely or surrendering all control over it. Instead, we need solutions that prioritize integrity in ways that balance privacy with the benefits of data sharing.
It’s not as if we haven’t made progress in better ways to manage online identity. Over the years, numerous trustworthy systems have been developed that could solve many of these problems. For example, imagine digital verification that works like a locked mobile phone—it works when you’re the one who can unlock and use it, but not if someone else grabs it from you. Or consider a storage device that holds all your credentials, like your driver’s license, professional certifications, and healthcare information, and lets you selectively share one without giving away everything at once. Imagine being able to share just a single cell in a table or a specific field in a file. These technologies already exist, and they could let you securely prove specific facts about yourself without surrendering control of your whole identity. This isn’t just theoretically better than traditional usernames and passwords; the technologies represent a fundamental shift in how we think about digital trust and verification.
Standards to do all these things emerged during the Web 2.0 era. We mostly haven’t used them because platform companies have been more interested in building barriers around user data and identity. They’ve used control of user identity as a key to market dominance and monetization. They’ve treated data as a corporate asset, and resisted open standards that would democratize data ownership and access. Closed, proprietary systems have better served their purposes.
There is another way. The Solid protocol, invented by Sir Tim Berners-Lee, represents a radical reimagining of how data operates online. Solid stands for “SOcial LInked Data.” At its core, it decouples data from applications by storing personal information in user-controlled “data wallets”: secure, personal data stores that users can host anywhere they choose. Applications can access specific data within these wallets, but users maintain ownership and control.
Solid is more than distributed data storage. This architecture inverts the current data ownership model. Instead of companies owning user data, users maintain a single source of truth for their personal information. It integrates and extends all those established identity standards and technologies mentioned earlier, and forms a comprehensive stack that places personal identity at the architectural center.
This identity-first paradigm means that every digital interaction begins with the authenticated individual who maintains control over their data. Applications become interchangeable views into user-owned data, rather than data silos themselves. This enables unprecedented interoperability, as services can securely access precisely the information they need while respecting user-defined boundaries.
Solid ensures that user intentions are transparently expressed and reliably enforced across the entire ecosystem. Instead of each application implementing its own custom authorization logic and access controls, Solid establishes a standardized declarative approach where permissions are explicitly defined through control lists or policies attached to resources. Users can specify who has access to what data with granular precision, using simple statements like “Alice can read this document” or “Bob can write to this folder.” These permission rules remain consistent, regardless of which application is accessing the data, eliminating the fragmentation and unpredictability of traditional authorization systems.
This architectural shift decouples applications from data infrastructure. Unlike Web 2.0 platforms like Facebook, which require massive back-end systems to store, process, and monetize user data, Solid applications can be lightweight and focused solely on functionality. Developers no longer need to build and maintain extensive data storage systems, surveillance infrastructure, or analytics pipelines. Instead, they can build specialized tools that request access to specific data in users’ wallets, with the heavy lifting of data storage and access control handled by the protocol itself.
Let’s take healthcare as an example. The current system forces patients to spread pieces of their medical history across countless proprietary databases controlled by insurance companies, hospital networks, and electronic health record vendors. Patients frustratingly become a patchwork rather than a person, because they often can’t access their own complete medical history, let alone correct mistakes. Meanwhile, those third-party databases suffer regular breaches. The Solid protocol enables a fundamentally different approach. Patients maintain their own comprehensive medical record, with data cryptographically signed by trusted providers, in their own data wallet. When visiting a new healthcare provider, patients can arrive with their complete, verifiable medical history rather than starting from zero or waiting for bureaucratic record transfers.
When a patient needs to see a specialist, they can grant temporary, specific access to relevant portions of their medical history. For example, a patient referred to a cardiologist could share only cardiac-related records and essential background information. Or, on the flip side, the patient can share new and rich sources of related data to the specialist, like health and nutrition data. The specialist, in turn, can add their findings and treatment recommendations directly to the patient’s wallet, with a cryptographic signature verifying medical credentials. This process eliminates dangerous information gaps while ensuring that patients maintain an appropriate role in who sees what about them and why.
When a patient—doctor relationship ends, the patient retains all records generated during that relationship—unlike today’s system where changing providers often means losing access to one’s historical records. The departing doctor’s signed contributions remain verifiable parts of the medical history, but they no longer have direct access to the patient’s wallet without explicit permission.
For insurance claims, patients can provide temporary, auditable access to specific information needed for processing—no more and no less. Insurance companies receive verified data directly relevant to claims but should not be expected to have uncontrolled hidden comprehensive profiles or retain information longer than safe under privacy regulations. This approach dramatically reduces unauthorized data use, risk of breaches (privacy and integrity), and administrative costs.
Perhaps most transformatively, this architecture enables patients to selectively participate in medical research while maintaining privacy. They could contribute anonymized or personalized data to studies matching their interests or conditions, with granular control over what information is shared and for how long. Researchers could gain access to larger, more diverse datasets while participants would maintain control over their information—creating a proper ethical model for advancing medical knowledge.
The implications extend far beyond healthcare. In financial services, customers could maintain verified transaction histories and creditworthiness credentials independently of credit bureaus. In education, students could collect verified credentials and portfolios that they truly own rather than relying on institutions’ siloed records. In employment, workers could maintain portable professional histories with verified credentials from past employers. In each case, Solid enables individuals to be the masters of their own data while allowing verification and selective sharing.
The economics of Web 2.0 pushed us toward centralized platforms and surveillance capitalism, but there has always been a better way. Solid brings different pieces together into a cohesive whole that enables the identity-first architecture we should have had all along. The protocol doesn’t just solve technical problems; it corrects the fundamental misalignment of incentives that has made the modern web increasingly hostile to both users and developers.
As we look to a future of increased digitization across all sectors of society, the need for this architectural shift becomes even more apparent. Individuals should be able to maintain and present their own verified digital identity and history, rather than being at the mercy of siloed institutional databases. The Solid protocol makes this future technically possible.
This essay was written with Davi Ottenheimer, and originally appeared on The Inrupt Blog.
It will be interesting to watch what will come of this private lawsuit:
Google on Thursday announced filing a lawsuit against the operators of the Badbox 2.0 botnet, which has ensnared more than 10 million devices running Android open source software.
These devices lack Google’s security protections, and the perpetrators pre-installed the Badbox 2.0 malware on them, to create a backdoor and abuse them for large-scale fraud and other illicit schemes.
This reminds me of Meta’s lawauit against Pegasus over its hack-for-hire software (which I wrote about here.) It’s a private company stepping into a regulatory void left by governments.
Abstract: The National Security Agency (NSA) reportedly paid and pressured technology companies to trick their customers into using vulnerable encryption products. This Article examines whether any of three theories removed the Fourth Amendment’s requirement that this be reasonable. The first is that a challenge to the encryption backdoor might fail for want of a search or seizure. The Article rejects this both because the Amendment reaches some vulnerabilities apart from the searches and seizures they enable and because the creation of this vulnerability was itself a search or seizure. The second is that the role of the technology companies might have brought this backdoor within the private-search doctrine. The Article criticizes the doctrine particularly its origins in Burdeau v. McDowelland argues that if it ever should apply, it should not here. The last is that the customers might have waived their Fourth Amendment rights under the third-party doctrine. The Article rejects this both because the customers were not on notice of the backdoor and because historical understandings of the Amendment would not have tolerated it. The Article concludes that none of these theories removed the Amendment’s reasonableness requirement.
Microsoft is using engineers in China to help maintain the Defense Department’s computer systems—with minimal supervision by U.S. personnel—leaving some of the nation’s most sensitive data vulnerable to hacking from its leading cyber adversary, a ProPublica investigation has found.
The arrangement, which was critical to Microsoft winning the federal government’s cloud computing business a decade ago, relies on U.S. citizens with security clearances to oversee the work and serve as a barrier against espionage and sabotage.
But these workers, known as “digital escorts,” often lack the technical expertise to police foreign engineers with far more advanced skills, ProPublica found. Some are former military personnel with little coding experience who are paid barely more than minimum wage for the work.
This sounds bad, but it’s the way the digital world works. Everything we do is international, deeply international. Making anything US-only is hard, and often infeasible.
EDITED TO ADD: Microsoft has stopped the practice.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
 Never expose your keys publicly!