In my last Week in Review post, I mentioned how much time I’ve been spending on AI-Driven Development Lifecycle (AI-DLC) workshops with customers this year. A common theme in those sessions is the need for better cost visibility. Teams are moving fast with AI, but as they go from experimenting to full production, finance and leadership really need to know who is using which resources and at what cost. That’s why I was so excited to see the launch of Amazon Bedrock new support for cost allocation by IAM user and role this week. This lets you tag IAM principals with attributes like team or cost center and then activate those tags in your Billing and Cost Management console. The resulting cost data flows into AWS Cost Explorer and the detailed Cost and Usage Report, giving you a clear line of sight into model inference spending. Whether you’re scaling agents across teams, tracking foundation model use by department, or running tools like Claude Code on Amazon Bedrock, this new feature is a game changer for tracking and managing your AI investments. You can get all the details on setting this up in the IAM principal cost allocation documentation.
Now, let’s get into this week’s AWS news…
Headlines Amazon Bedrock now offers Claude Mythos Preview Anthropic’s most sophisticated AI model to date is now available on Amazon Bedrock as a gated research preview through Project Glasswing. Claude Mythos introduces a new model class focused on cybersecurity, capable of identifying sophisticated security vulnerabilities in software, analyzing large codebases, and delivering state of the art performance across cybersecurity, coding, and complex reasoning tasks. Security teams can use it to discover and address vulnerabilities in critical software before threats emerge. Access is currently limited to allowlisted organizations, with Anthropic and AWS prioritizing internet critical companies and open source maintainers.
AWS Agent Registry for centralized agent discovery and governance now in preview AWS launched Agent Registry through Amazon Bedrock AgentCore, providing organizations with a private catalog for discovering and managing AI agents, tools, skills, MCP servers, and custom resources. The registry helps teams locate existing capabilities rather than duplicating them, with semantic and keyword search, approval workflows, and CloudTrail audit trails. It is accessible via the AgentCore Console, AWS CLI, SDK, and as an MCP server queryable from IDEs.
Last week’s launches Here are some launches and updates from this past week that caught my attention:
Announcing Amazon S3 Files, making S3 buckets accessible as file systems — Amazon S3 Files transforms S3 buckets into shared file systems that connect any AWS compute resource directly with your S3 data. Built on Amazon EFS technology, it delivers full file system semantics with low latency performance, caching actively used data and providing multiple terabytes per second of aggregate read throughput. Applications can access S3 data through both file system and S3 APIs simultaneously without code modifications or data migration.
Amazon OpenSearch Service supports Managed Prometheus and agent tracing —Amazon OpenSearch Service now provides a unified observability platform that consolidates metrics, logs, traces, and AI agent tracing into a single interface. The update includes native Prometheus integration with direct PromQL query support, RED metrics monitoring, and OpenTelemetry GenAI semantic convention support for LLM execution visibility. Operations teams can correlate slow traces to logs and overlay Prometheus metrics on dashboards without switching between tools.
Amazon WorkSpaces Advisor now available for AI powered troubleshooting— AWS launched Amazon WorkSpaces Advisor, an AI powered administrative tool that uses generative AI to help IT administrators troubleshoot Amazon WorkSpaces Personal deployments. It analyzes WorkSpace configurations, detects problems automatically, and provides actionable recommendations to restore service and optimize performance.
Amazon Braket adds support for Rigetti’s 108 qubit Cepheus QPU — Amazon Braket now offers access to Rigetti’s Cepheus-1-108Q device, the first 100+ qubit superconducting quantum processor on the platform. The modular design features twelve 9 qubit chiplets with CZ gates that offer enhanced resilience to phase errors. It supports multiple frameworks including Braket SDK, Qiskit, CUDA-Q, and Pennylane, with pulse level control for researchers.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news Here are some additional posts and resources that you might find interesting:
Understanding Amazon Bedrock model lifecycle — Machine learning blog post that walks through the stages foundation models go through in Bedrock from availability through deprecation, helping teams plan for model updates and manage version dependencies in production.
Deploy OpenClaw on AWS: Choose the right options for your AI workload — Builder Center guide comparing four AWS deployment options for OpenClaw: Amazon Lightsail for individual developers, Amazon EC2 for startups needing deeper AWS integration, Amazon Bedrock AgentCore for serverless multiuser scenarios, and Amazon EKS for enterprises requiring VM level isolation and advanced orchestration.
We’re bringing back the Kiro startup credits program — Kiro is relaunching its startup credits initiative, offering eligible early stage companies complimentary access to Kiro Pro+ for up to one year. The three tier program (Starter, Growth, Scale) provides 2 to 30 users based on team size, with rolling applications accepted globally.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
What’s Next with AWS(April 28, Virtual) Join this livestream at 9am PT for a candid discussion about how agentic AI is transforming how businesses operate. Featuring AWS CEO Matt Garman, SVP Colleen Aubrey, and OpenAI leaders discussing emerging agent capabilities, Amazon’s internal experiences, and new agentic solutions and platform capabilities.
Amazon OpenSearch Service powers observability workflows for organizations, giving their Site Reliability Engineering (SRE) and DevOps teams a single pane of glass to aggregate and analyze telemetry data. During incidents, correlating signals and identifying root causes demand deep expertise in log analytics and hours of manual work. Identifying the root cause remains largely manual. For many teams, this is the bottleneck that delays service recovery and burns engineering resources.
We recently showed how to build an Observability Agent using Amazon OpenSearch Service and Amazon Bedrock to reduce Mean time to Resolution (MTTR). Now, Amazon OpenSearch Service brings many of these functions to the OpenSearch UI—no additional infrastructure required. Three new agentic AI features are offered to streamline and accelerate MTTR:
An Agentic Chatbot that can access the context and the underlying data that you’re looking at, apply agentic reasoning, and use tools to query data and generate insights on your behalf.
An Investigation Agent that deep-dives across signal data with hypothesis-driven analysis, explaining its reasoning at every step.
An Agentic Memory that supports both agents, so their accuracy and speed improve the more you use them.
In this post, we show how these capabilities work together to help engineers go from alert to root cause in minutes. We also walk through a sample scenario where the Investigation Agent automatically correlates data across multiple indices to surface a root cause hypothesis.
How the agentic AI capabilities work together
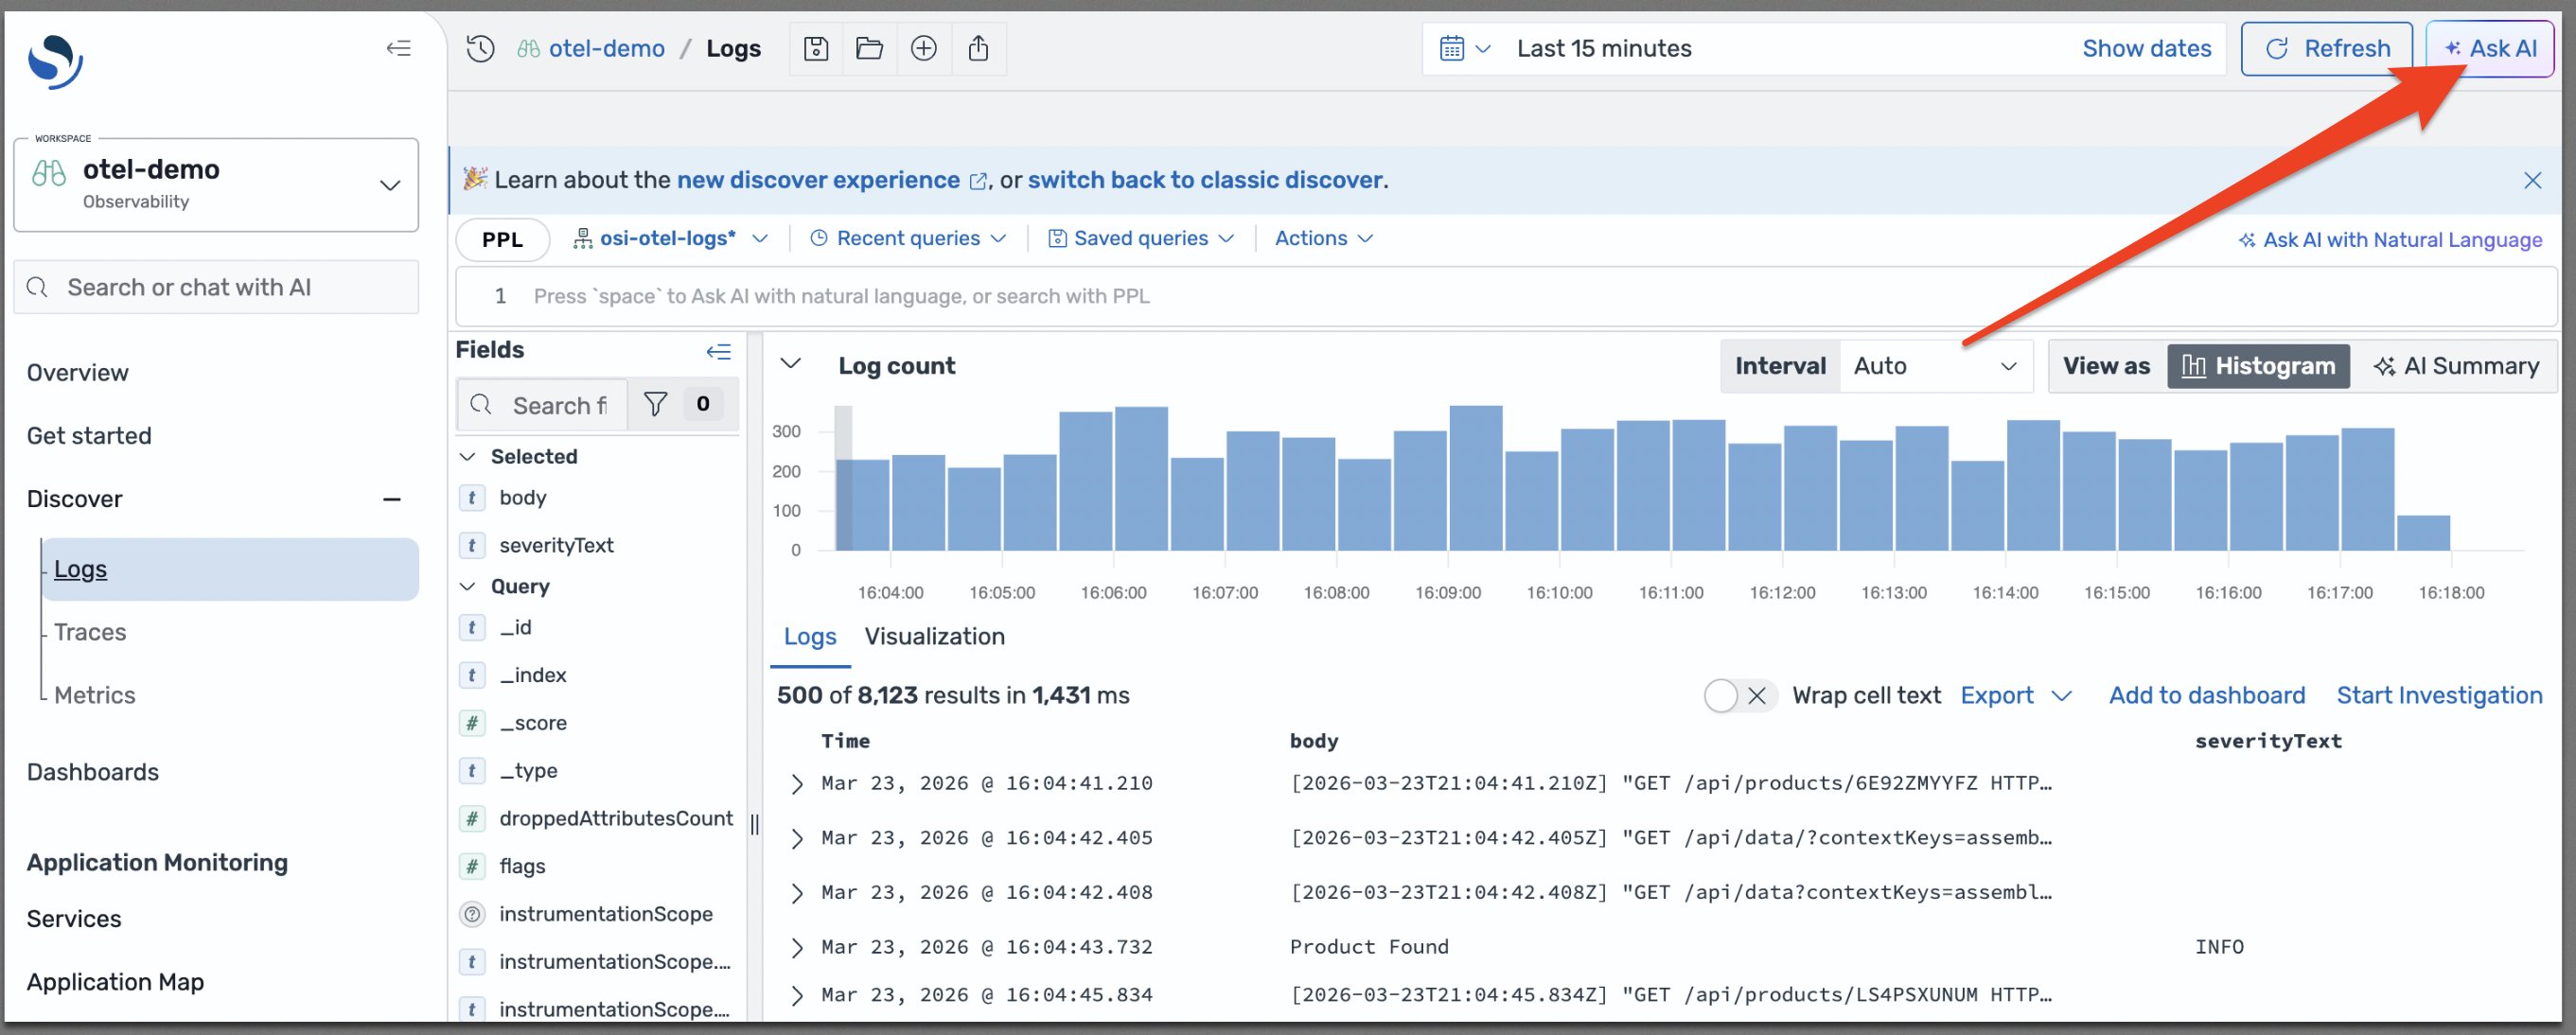
These AI capabilities are accessible from OpenSearch UI through an Ask AI button, as shown in the following diagram, which gives an entry point for the Agentic Chatbot.
Agentic Chatbot
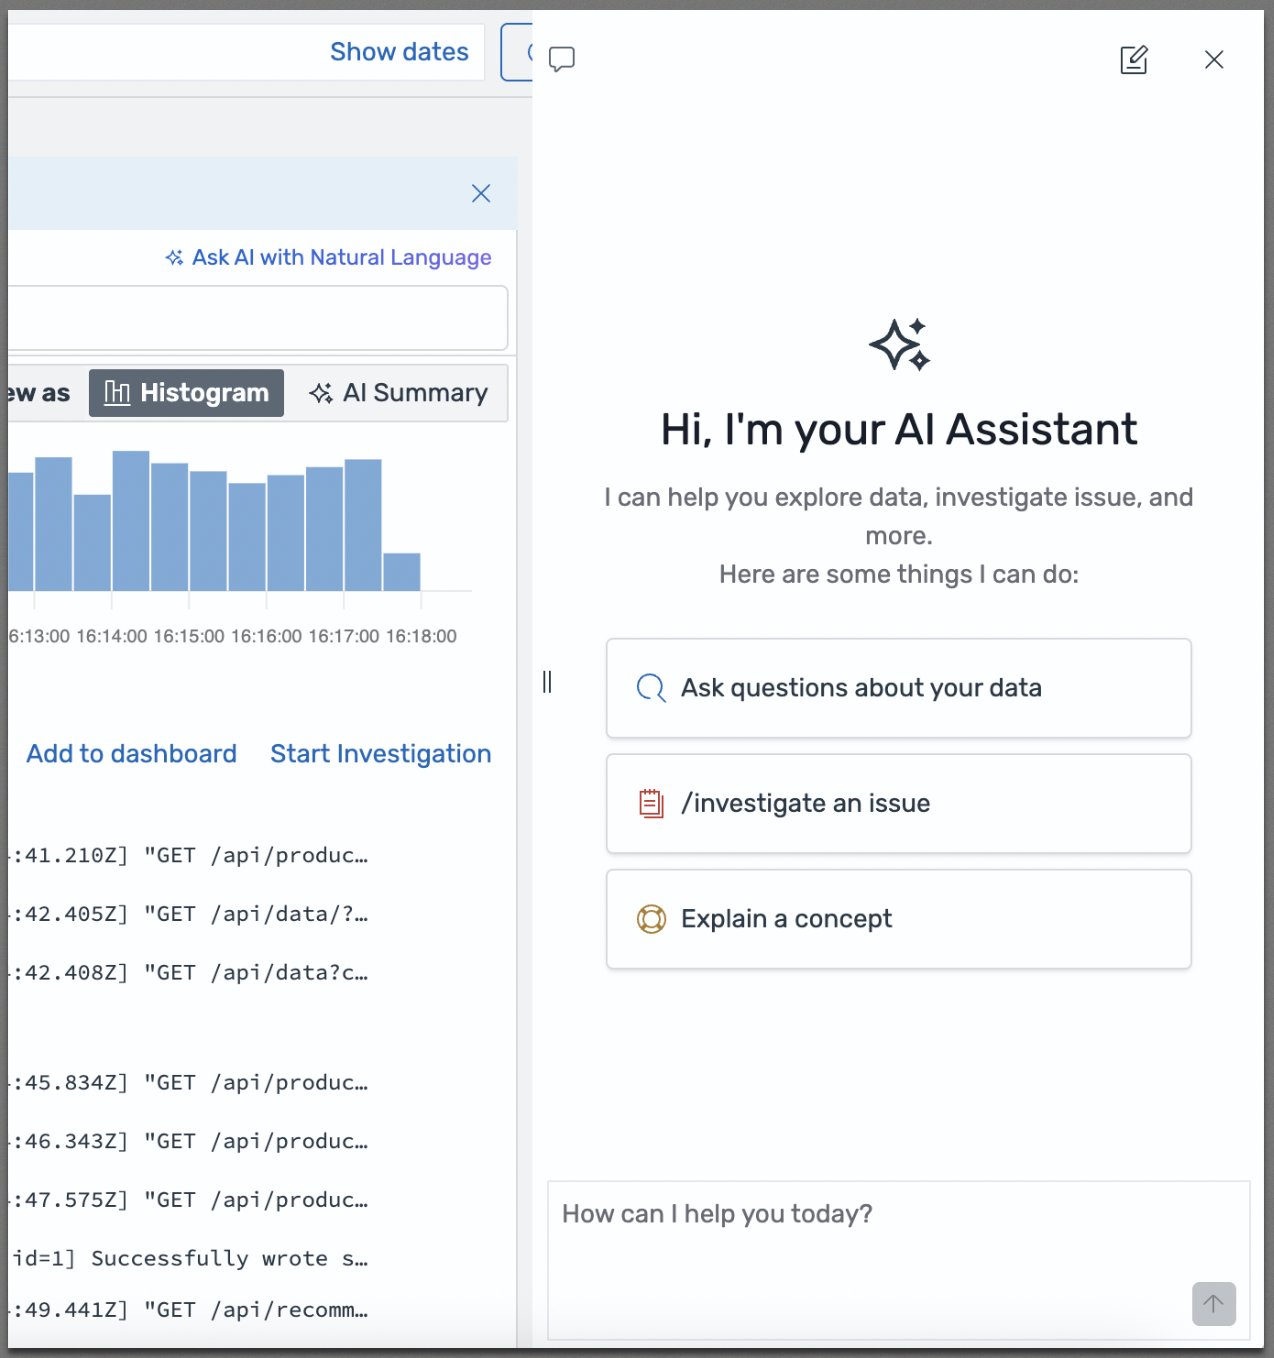
To open the chatbot interface, choose Ask AI.
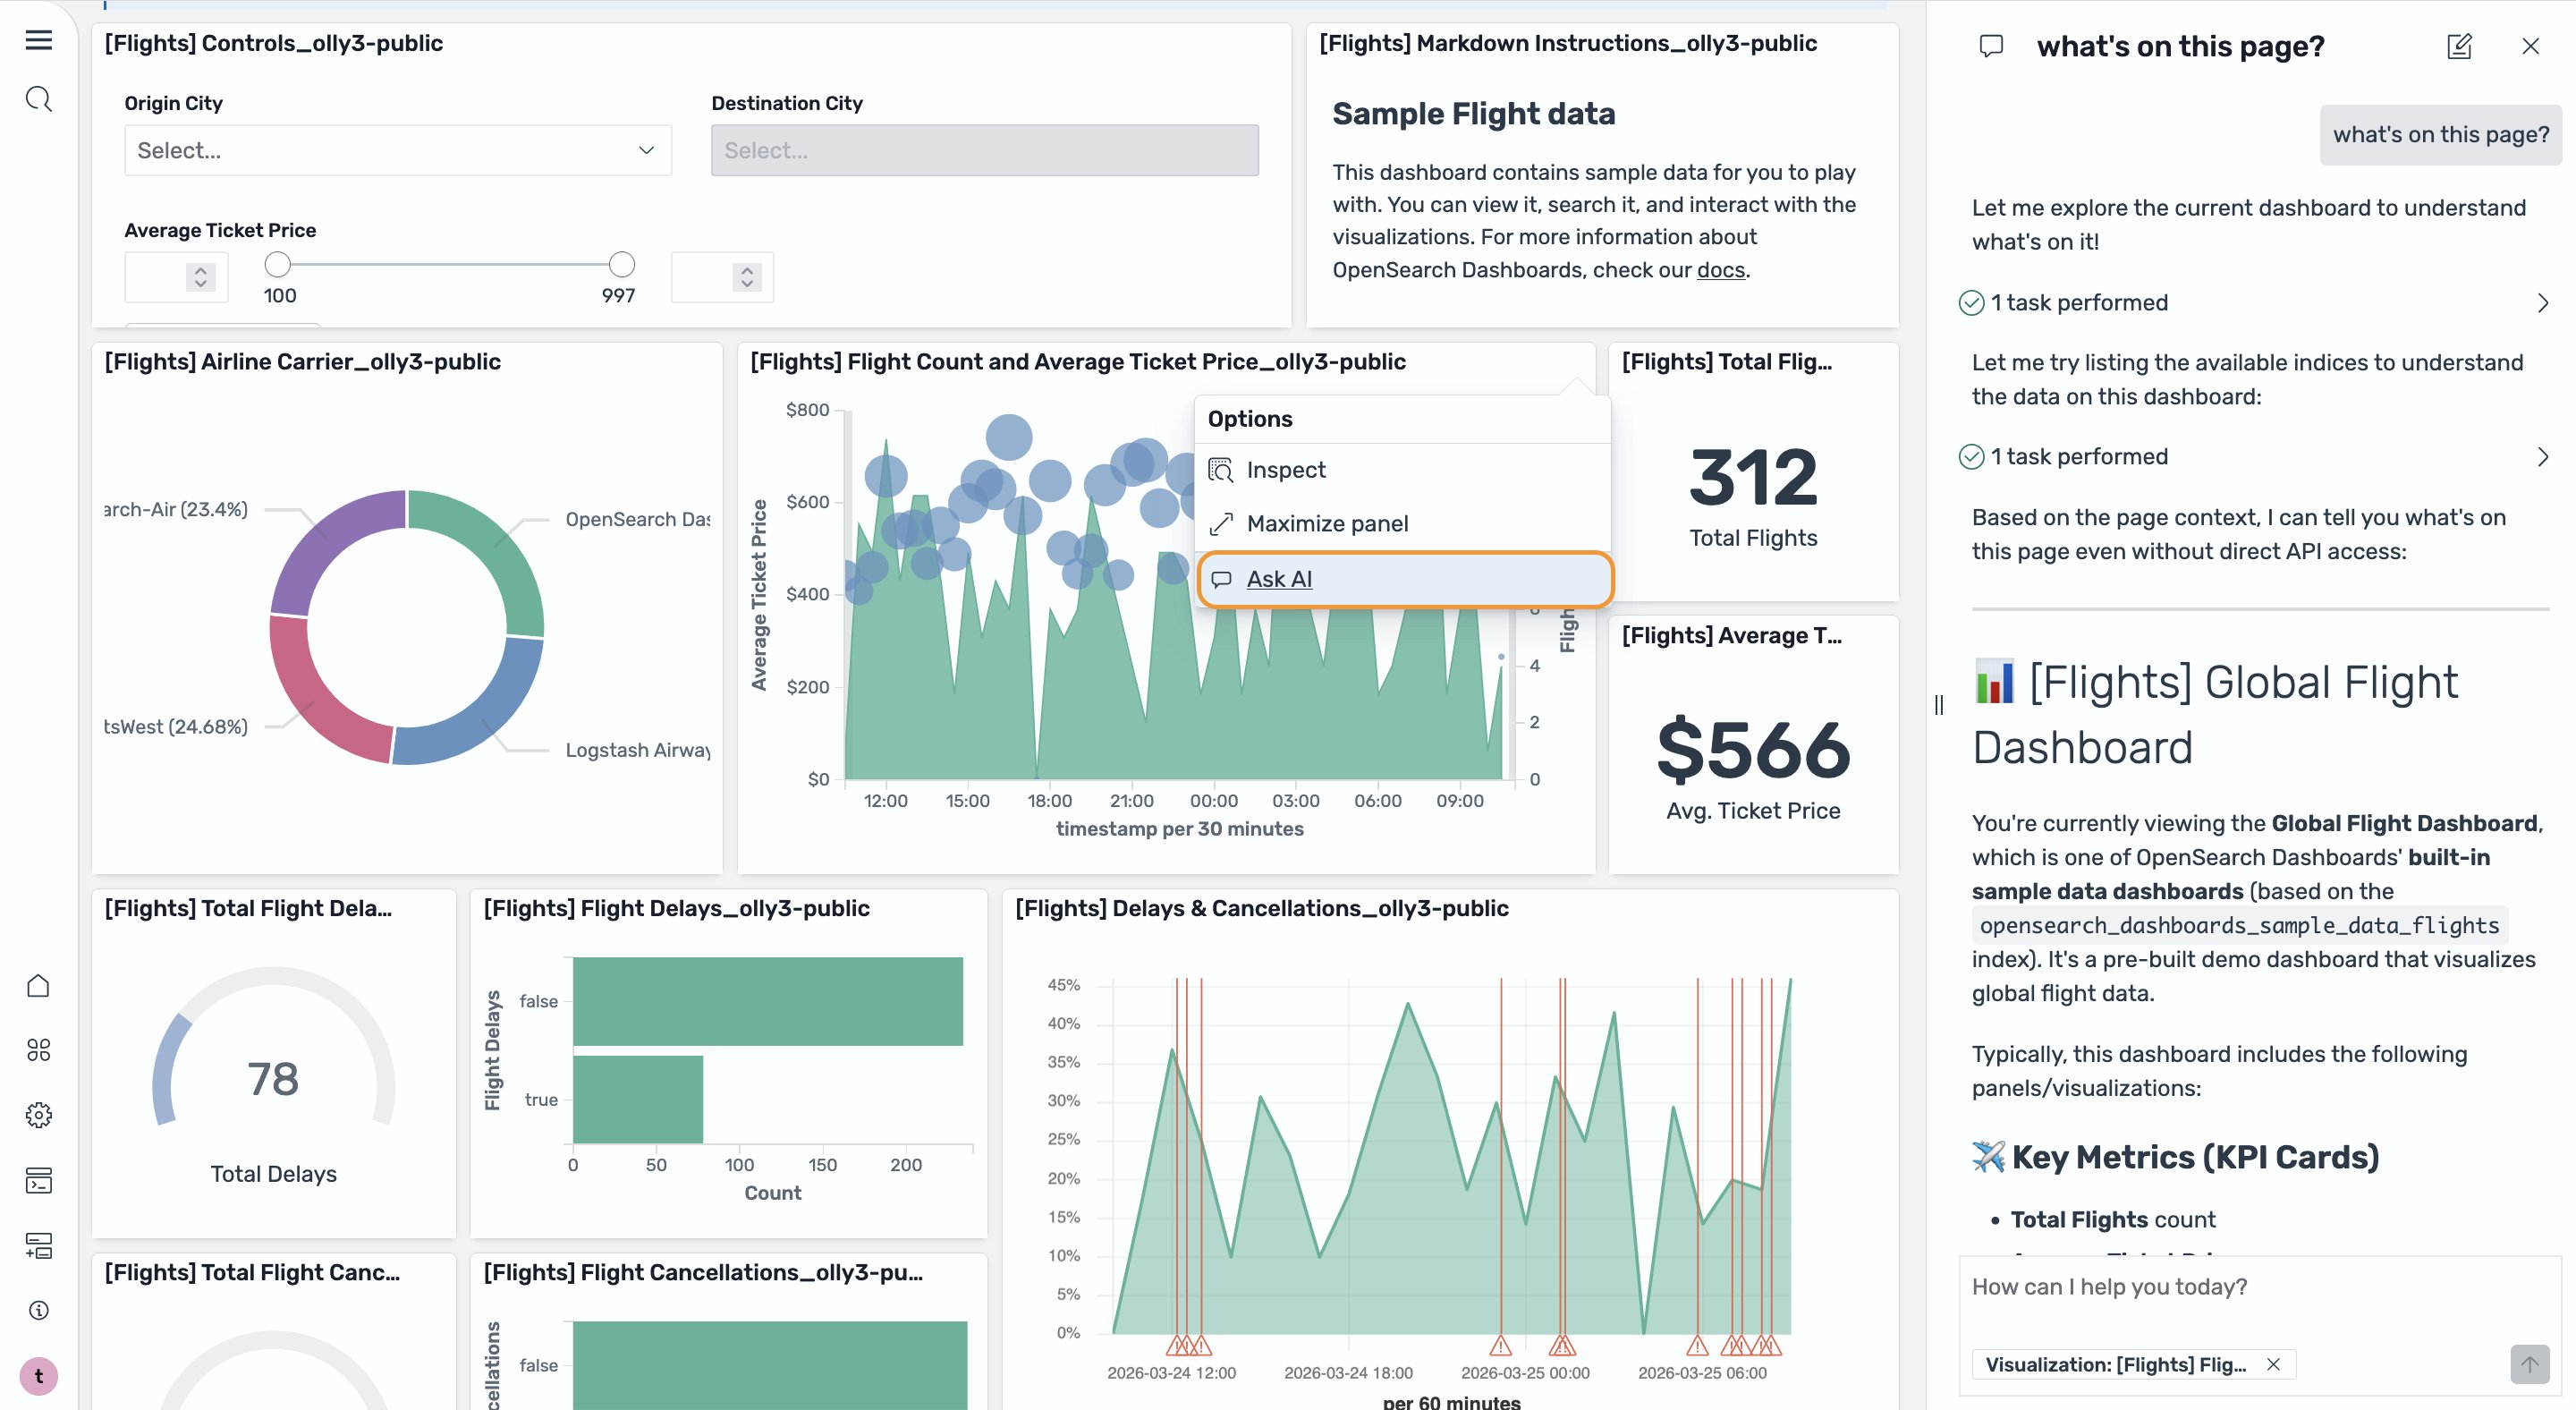
The chatbot understands the context of the current page, so it understands what you’re looking at before you ask a question. You can ask questions about your data, initiate an investigation, or ask the chatbot to explain a concept. After it understands your request, the chatbot plans and uses tools to access data, including generating and running queries in the Discover page, and applies reasoning to produce a data-driven answer. You can also use the chatbot in the Dashboard page, initiating conversations from a particular visualization to get a summary as shown in the following image.
Investigation agent
Many incidents are too complex to resolve with one or two queries. Now you can get the help of the investigation agent to handle these complex situations. The investigation agent uses the plan-execute-reflect agent, which is designed for solving complex tasks that require iterative reasoning and step-by-step execution. It uses a Large Language Model (LLM) as a planner and another LLM as an executor. When an engineer identifies a suspicious observation, like an error rate spike or a latency anomaly, they can ask the investigation agent to investigate. One of the important steps the investigation agent performs is re-evaluation. The agent, after executing each step, reevaluates the plan using the planner and the intermediate results. The planner can adjust the plan if necessary or skip a step or dynamically add steps based on this new information. Using the planner, the agent generates a root cause analysis report led by the most likely hypothesis and recommendations, with full agent traces showing every reasoning step, all findings, and how they support the final hypotheses. You can provide feedback, add your own findings, iterate on the investigation goal, and review and validate each step of the agent’s reasoning. This approach mirrors how experienced incident responders work, but completes automatically in minutes. You can also use the “/investigate” slash command to initiate an investigation directly from the chatbot, building on an ongoing conversation or starting with a different investigation goal.
Agent in action
Automatic query generation
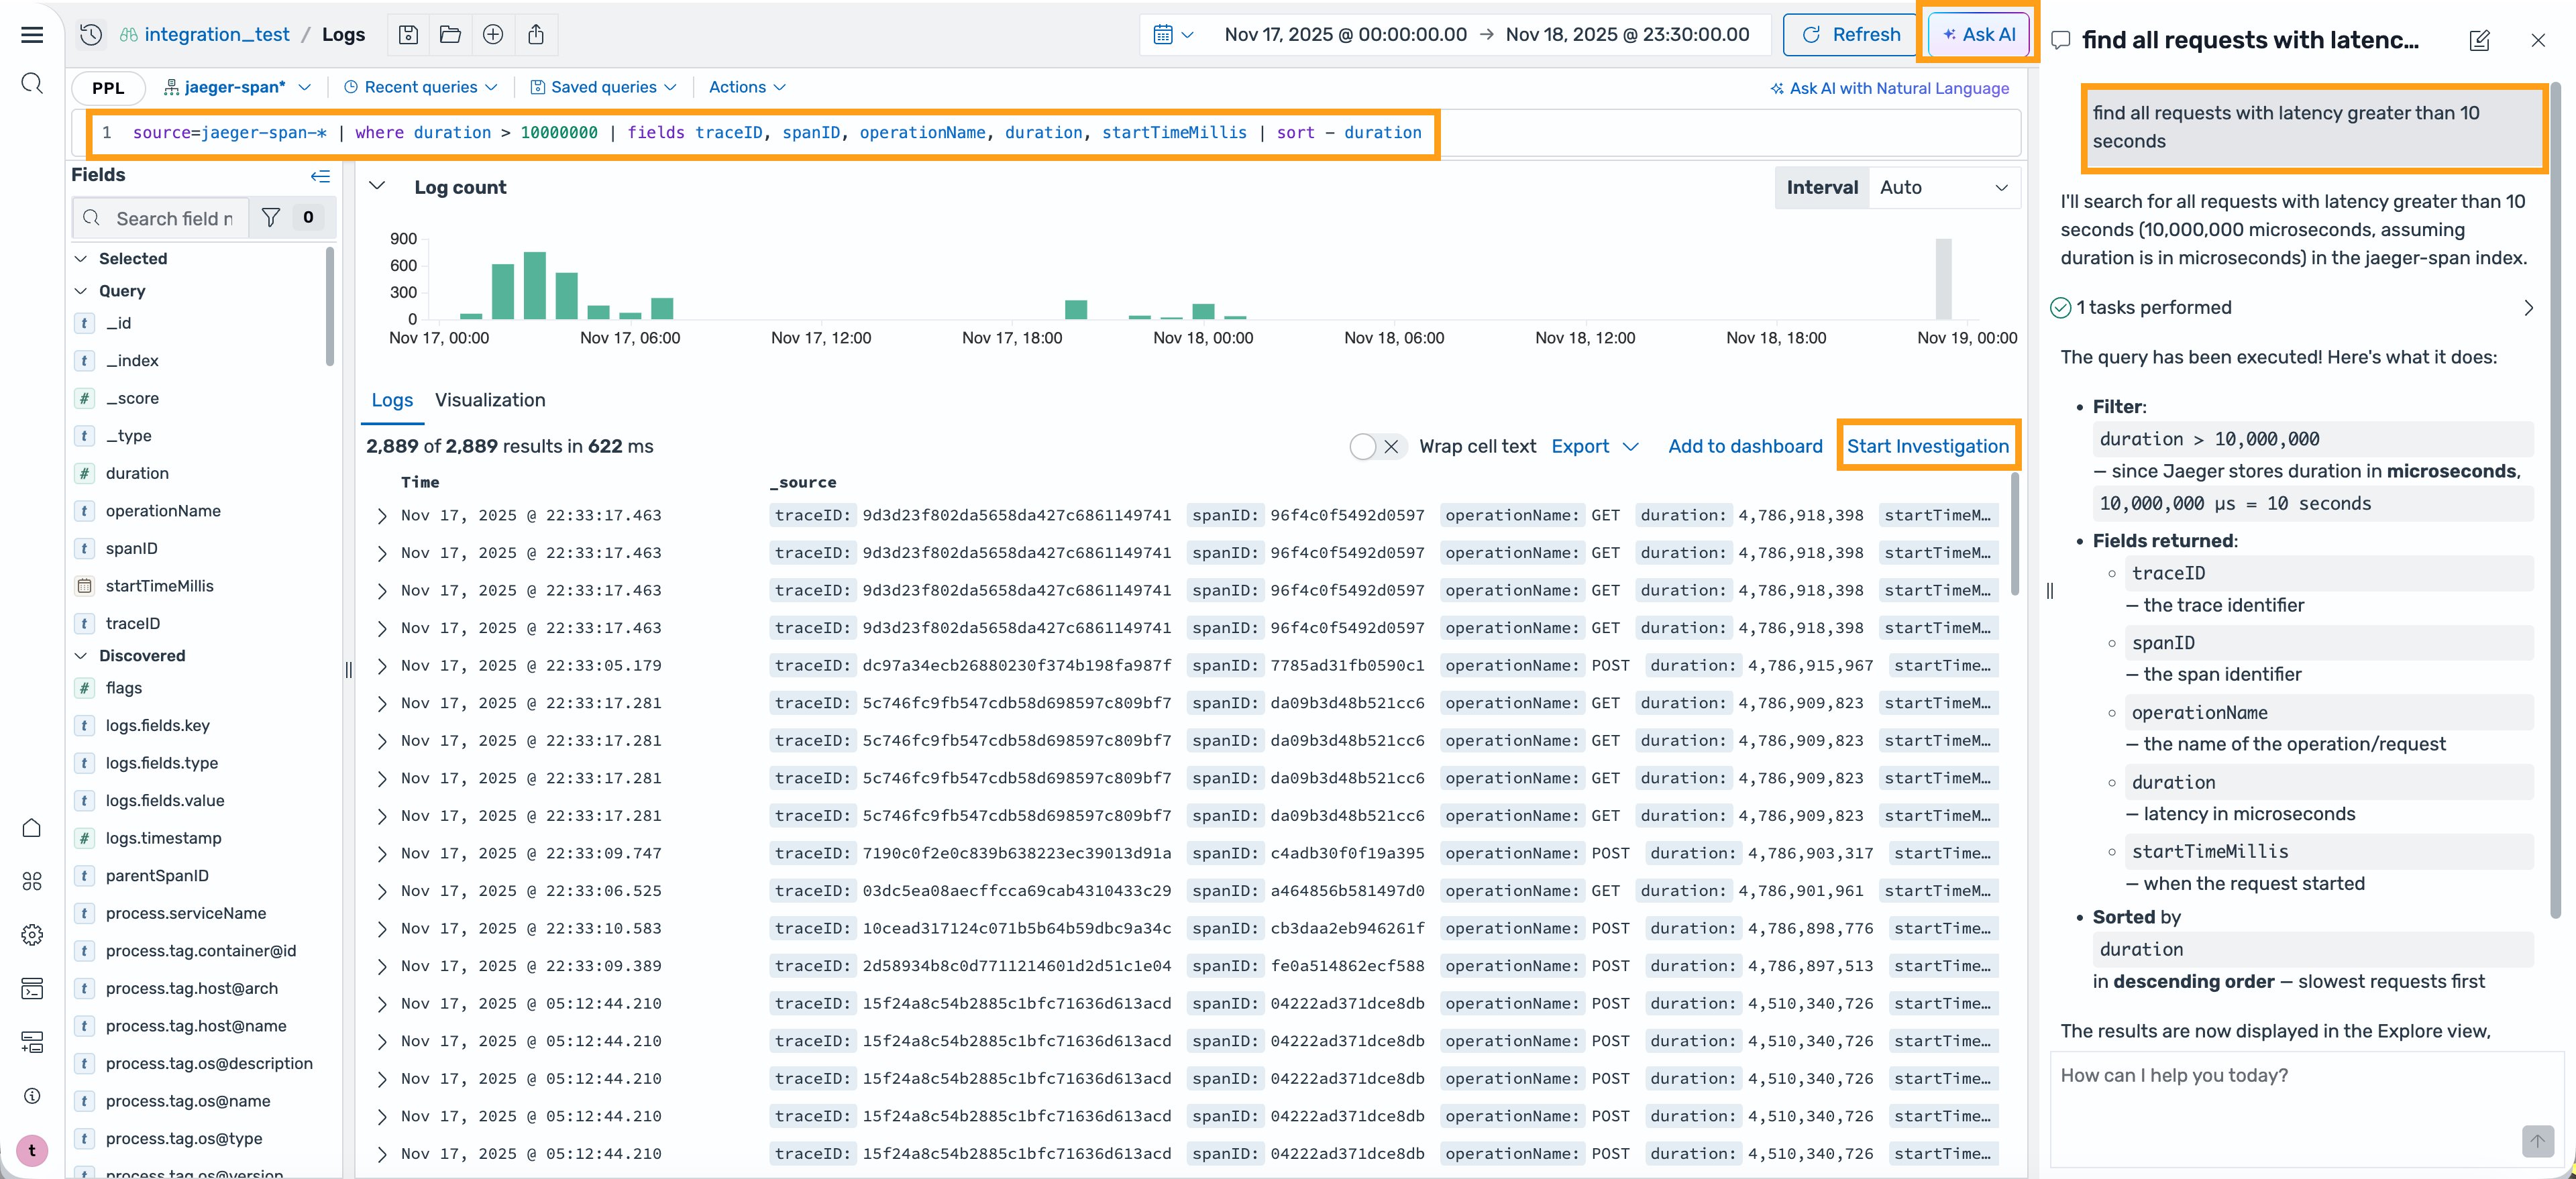
Consider a situation where you’re an SRE or DevOps engineer and received an alert that a key service is experiencing elevated latency. You log in to the OpenSearch UI, navigate to the Discover page, and select the Ask AI button. Without any expertise in the Piped Processing Language (PPL) query language, you enter the question “find all requests with latency greater than 10 seconds”. The chatbot understands the context and the data that you’re looking at, thinks through the request, generates the right PPL command, and updates it in the query bar to get you the results. And if the query runs into any errors, the chatbot can learn about the error, self-correct, and iterate on the query to get the results for you.
Investigation and investigation management
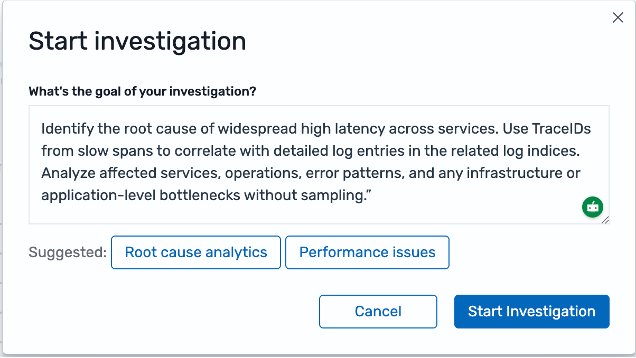
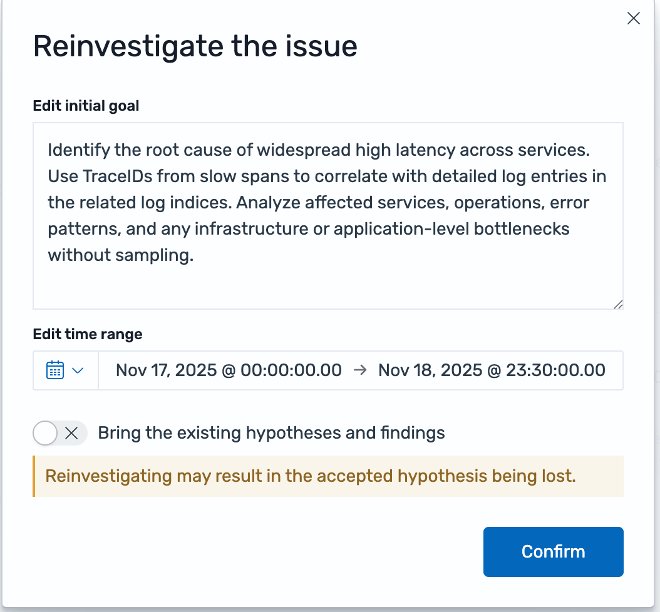
For complex incidents that normally require manually analyzing and correlating multiple logs for the possible root cause, you can choose Start Investigation to initiate the investigation agent. You can provide a goal for the investigation, along with any context or hypothesis that you want to instruct the investigation. For example, “identify the root cause of widespread high latency across services. Use TraceIDs from slow spans to correlate with detailed log entries in the related log indices. Analyze affected services, operations, error patterns, and any infrastructure or application-level bottlenecks without sampling”.
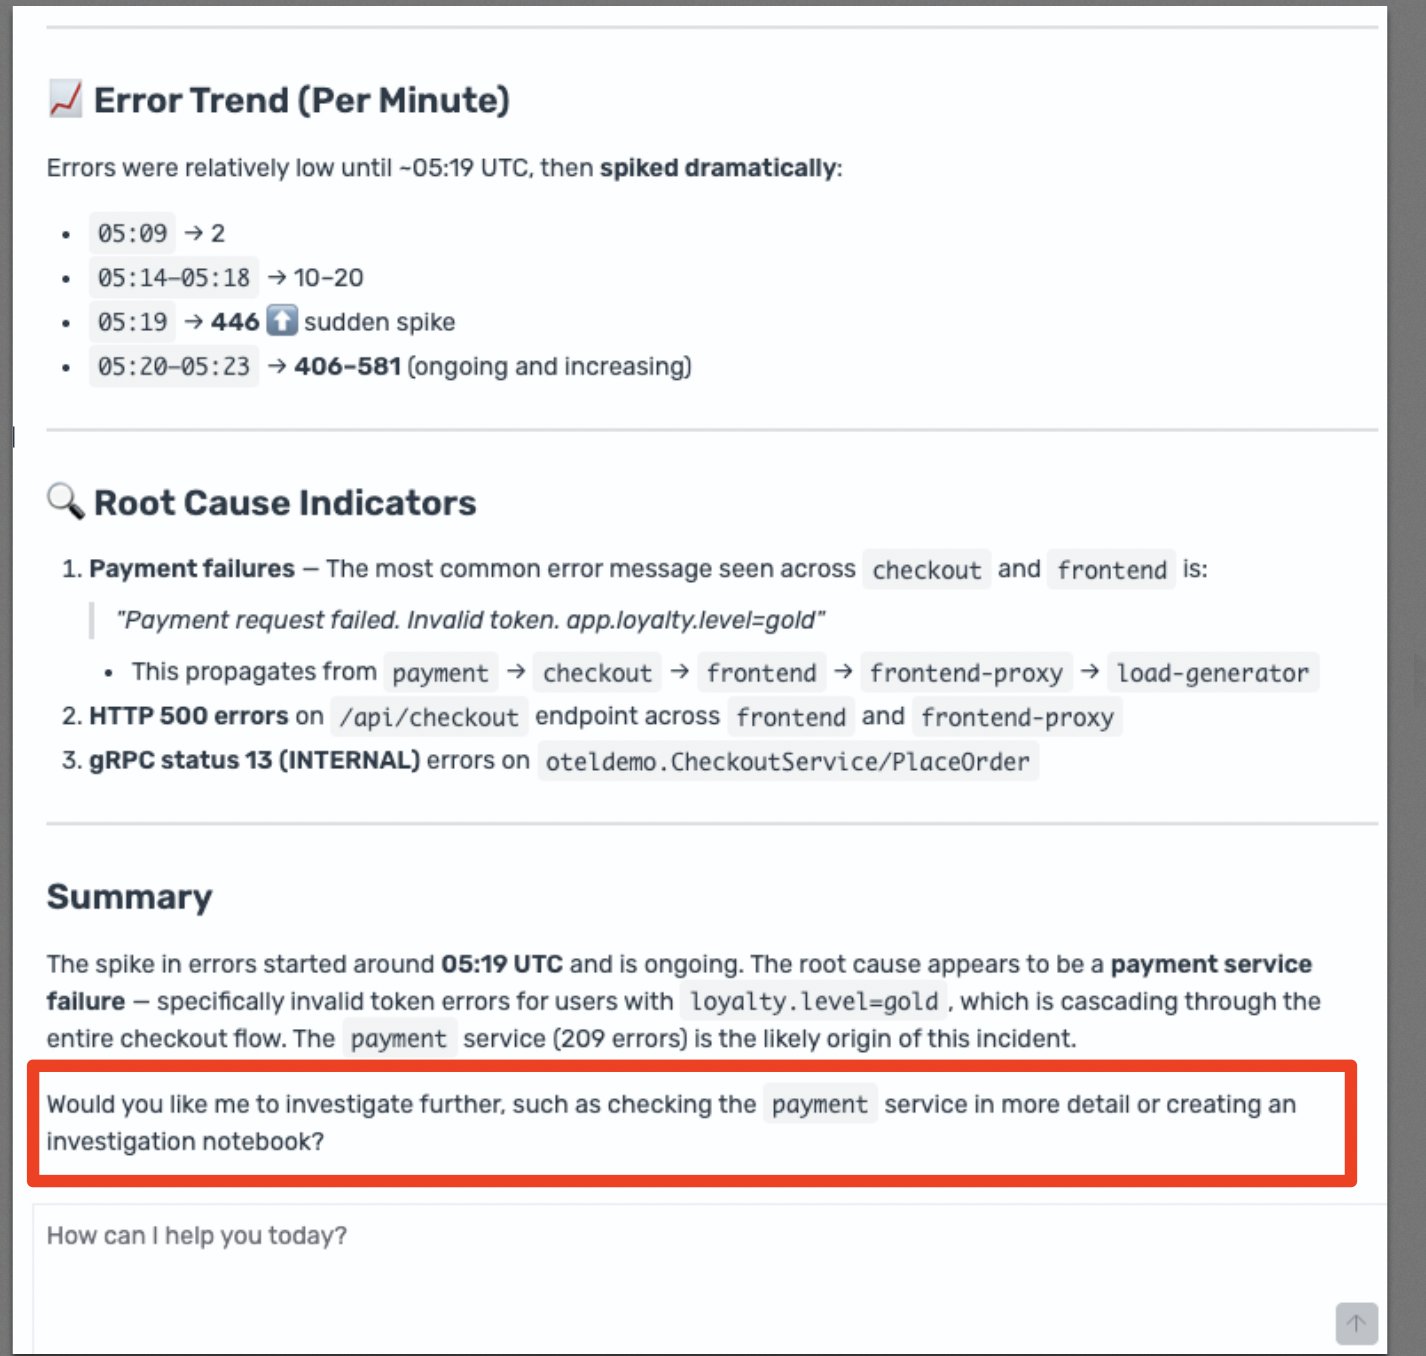
The agent, as part of the conversation, will offer to investigate any issue that you’re trying to debug.
The agent sets goals for itself along with any other relevant information like indices, associated time range, and other, and asks for your confirmation before creating a Notebook for this investigation. A Notebook is a way within the OpenSearch UI to develop a rich report that’s live and collaborative. This helps with the management of the investigation and allows for reinvestigation at a later date if necessary.
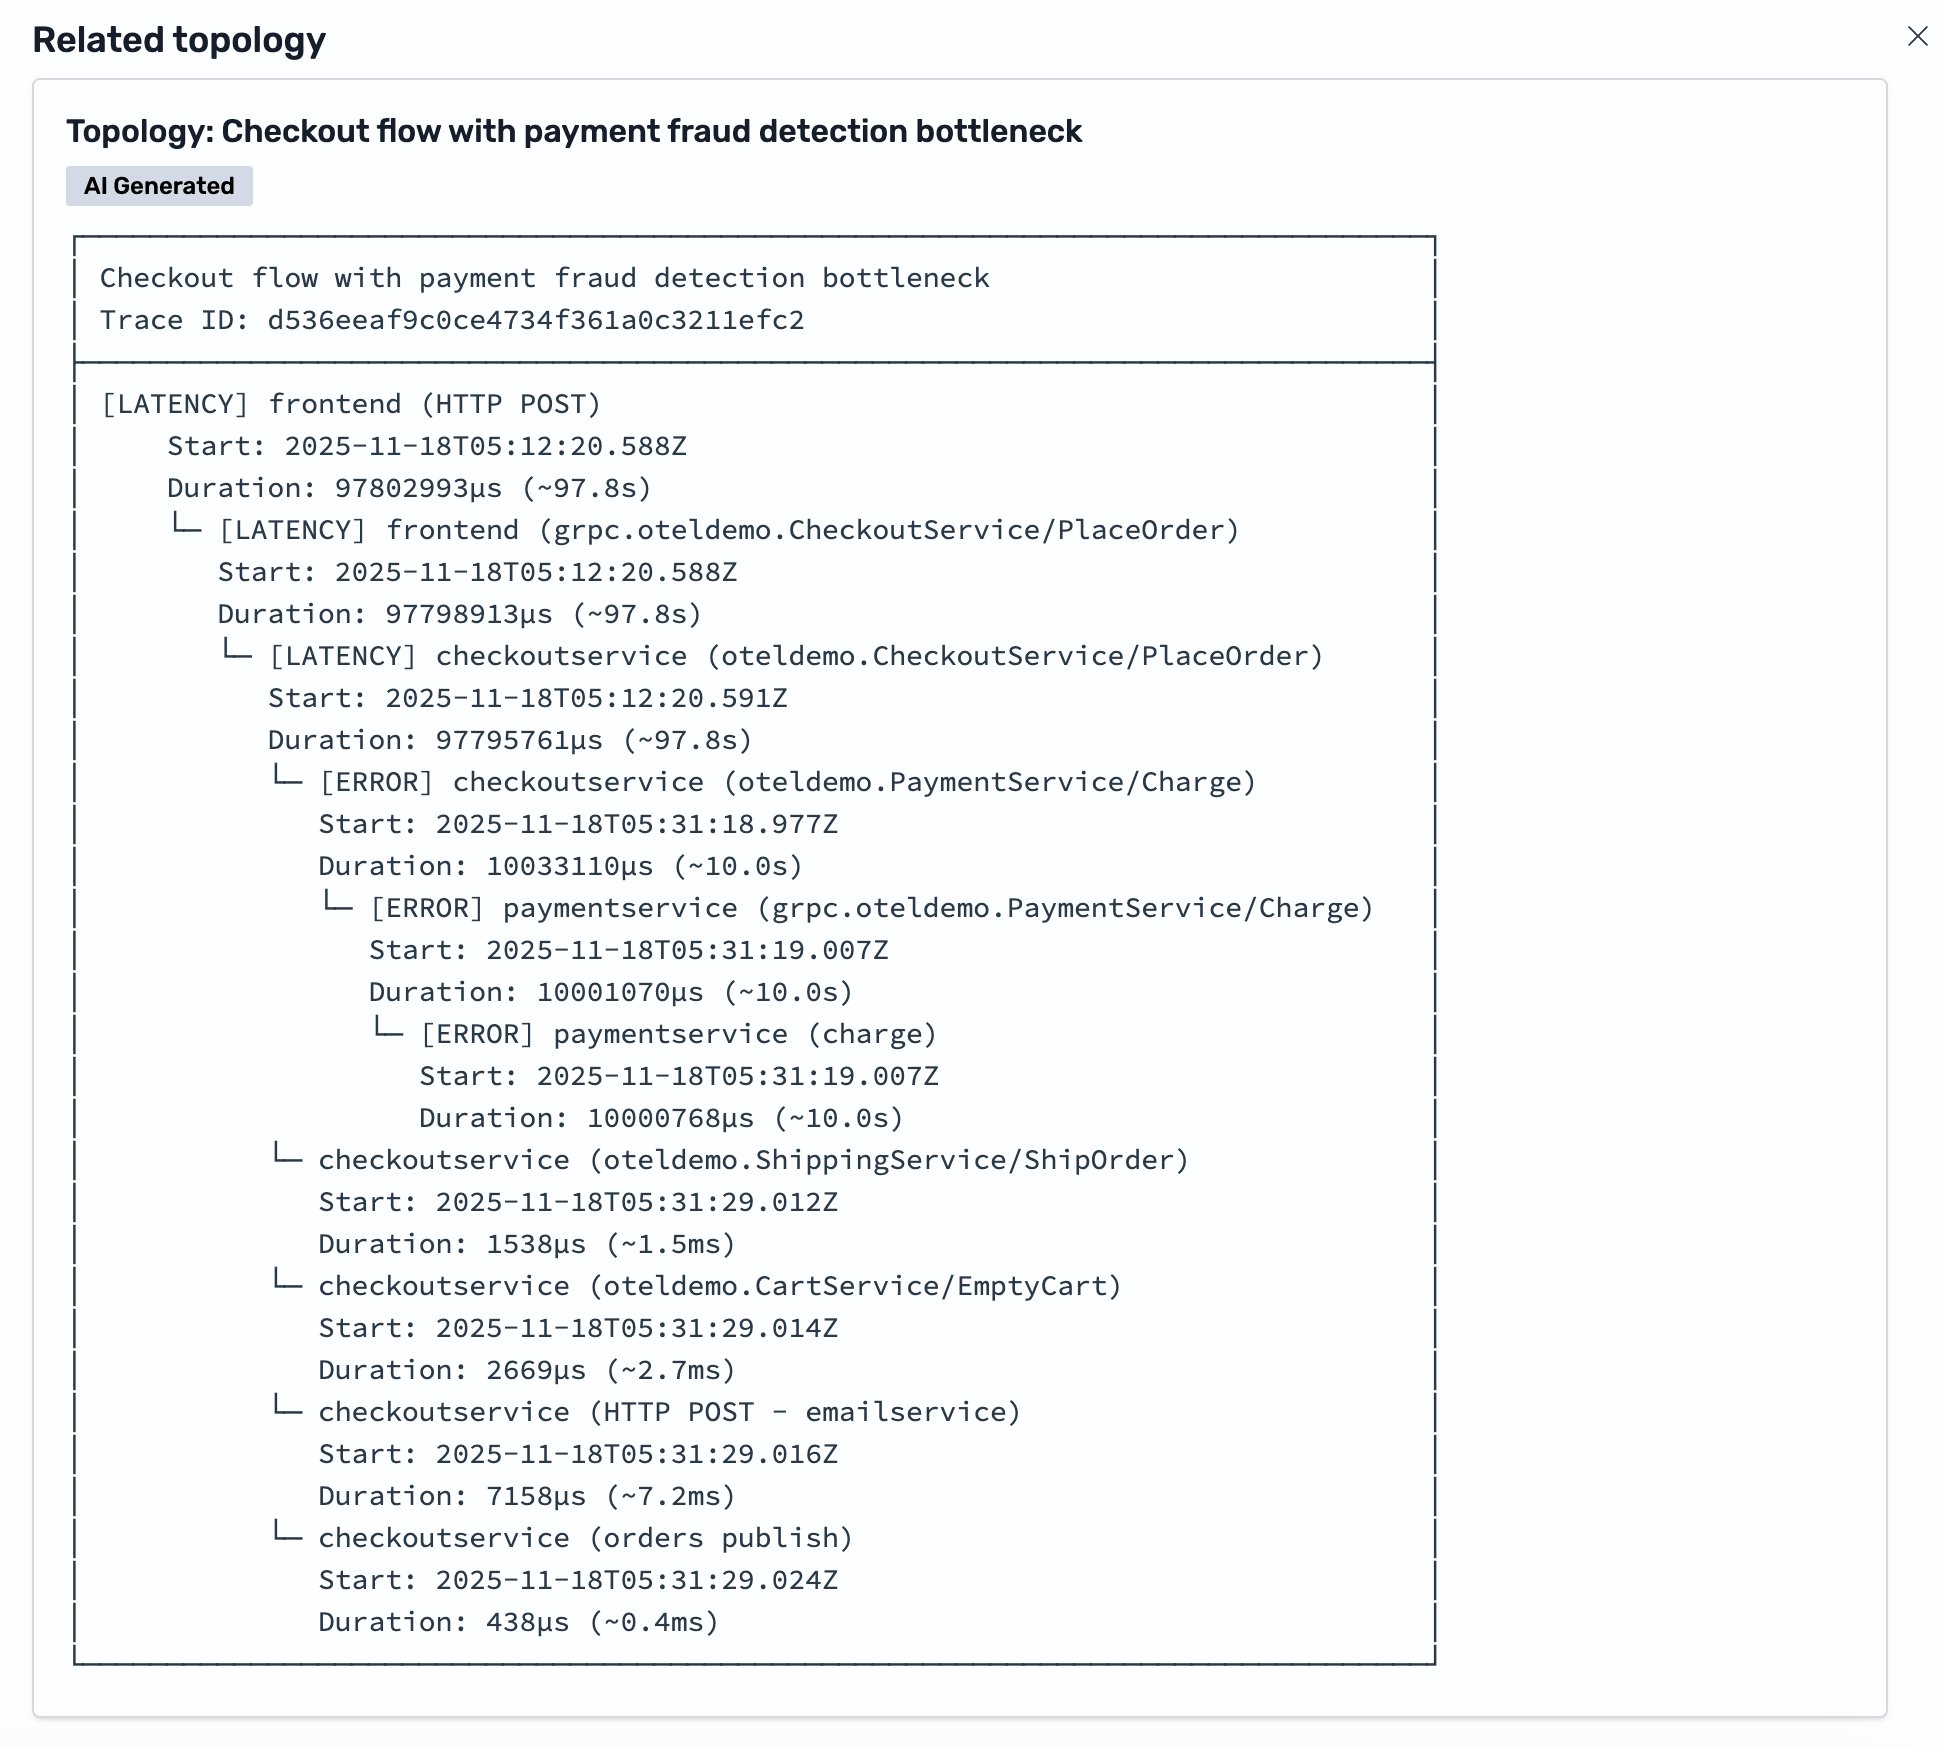
After the investigation starts, the agent will perform a quick analysis by log sequence and data distribution to surface outliers. Then, it will plan for the investigation into a series of actions, and then performs each action, such as query for a specific log type and time range. It will reflect on the results at every step, and iterate on the plan until it reaches the most likely hypotheses. Intermediate results will appear on the same page as the agent works so that you can follow the reasoning in real time. For example, you find that the Investigation Agent accurately mapped out the service topology and used it as a key intermediary steps for the investigation.
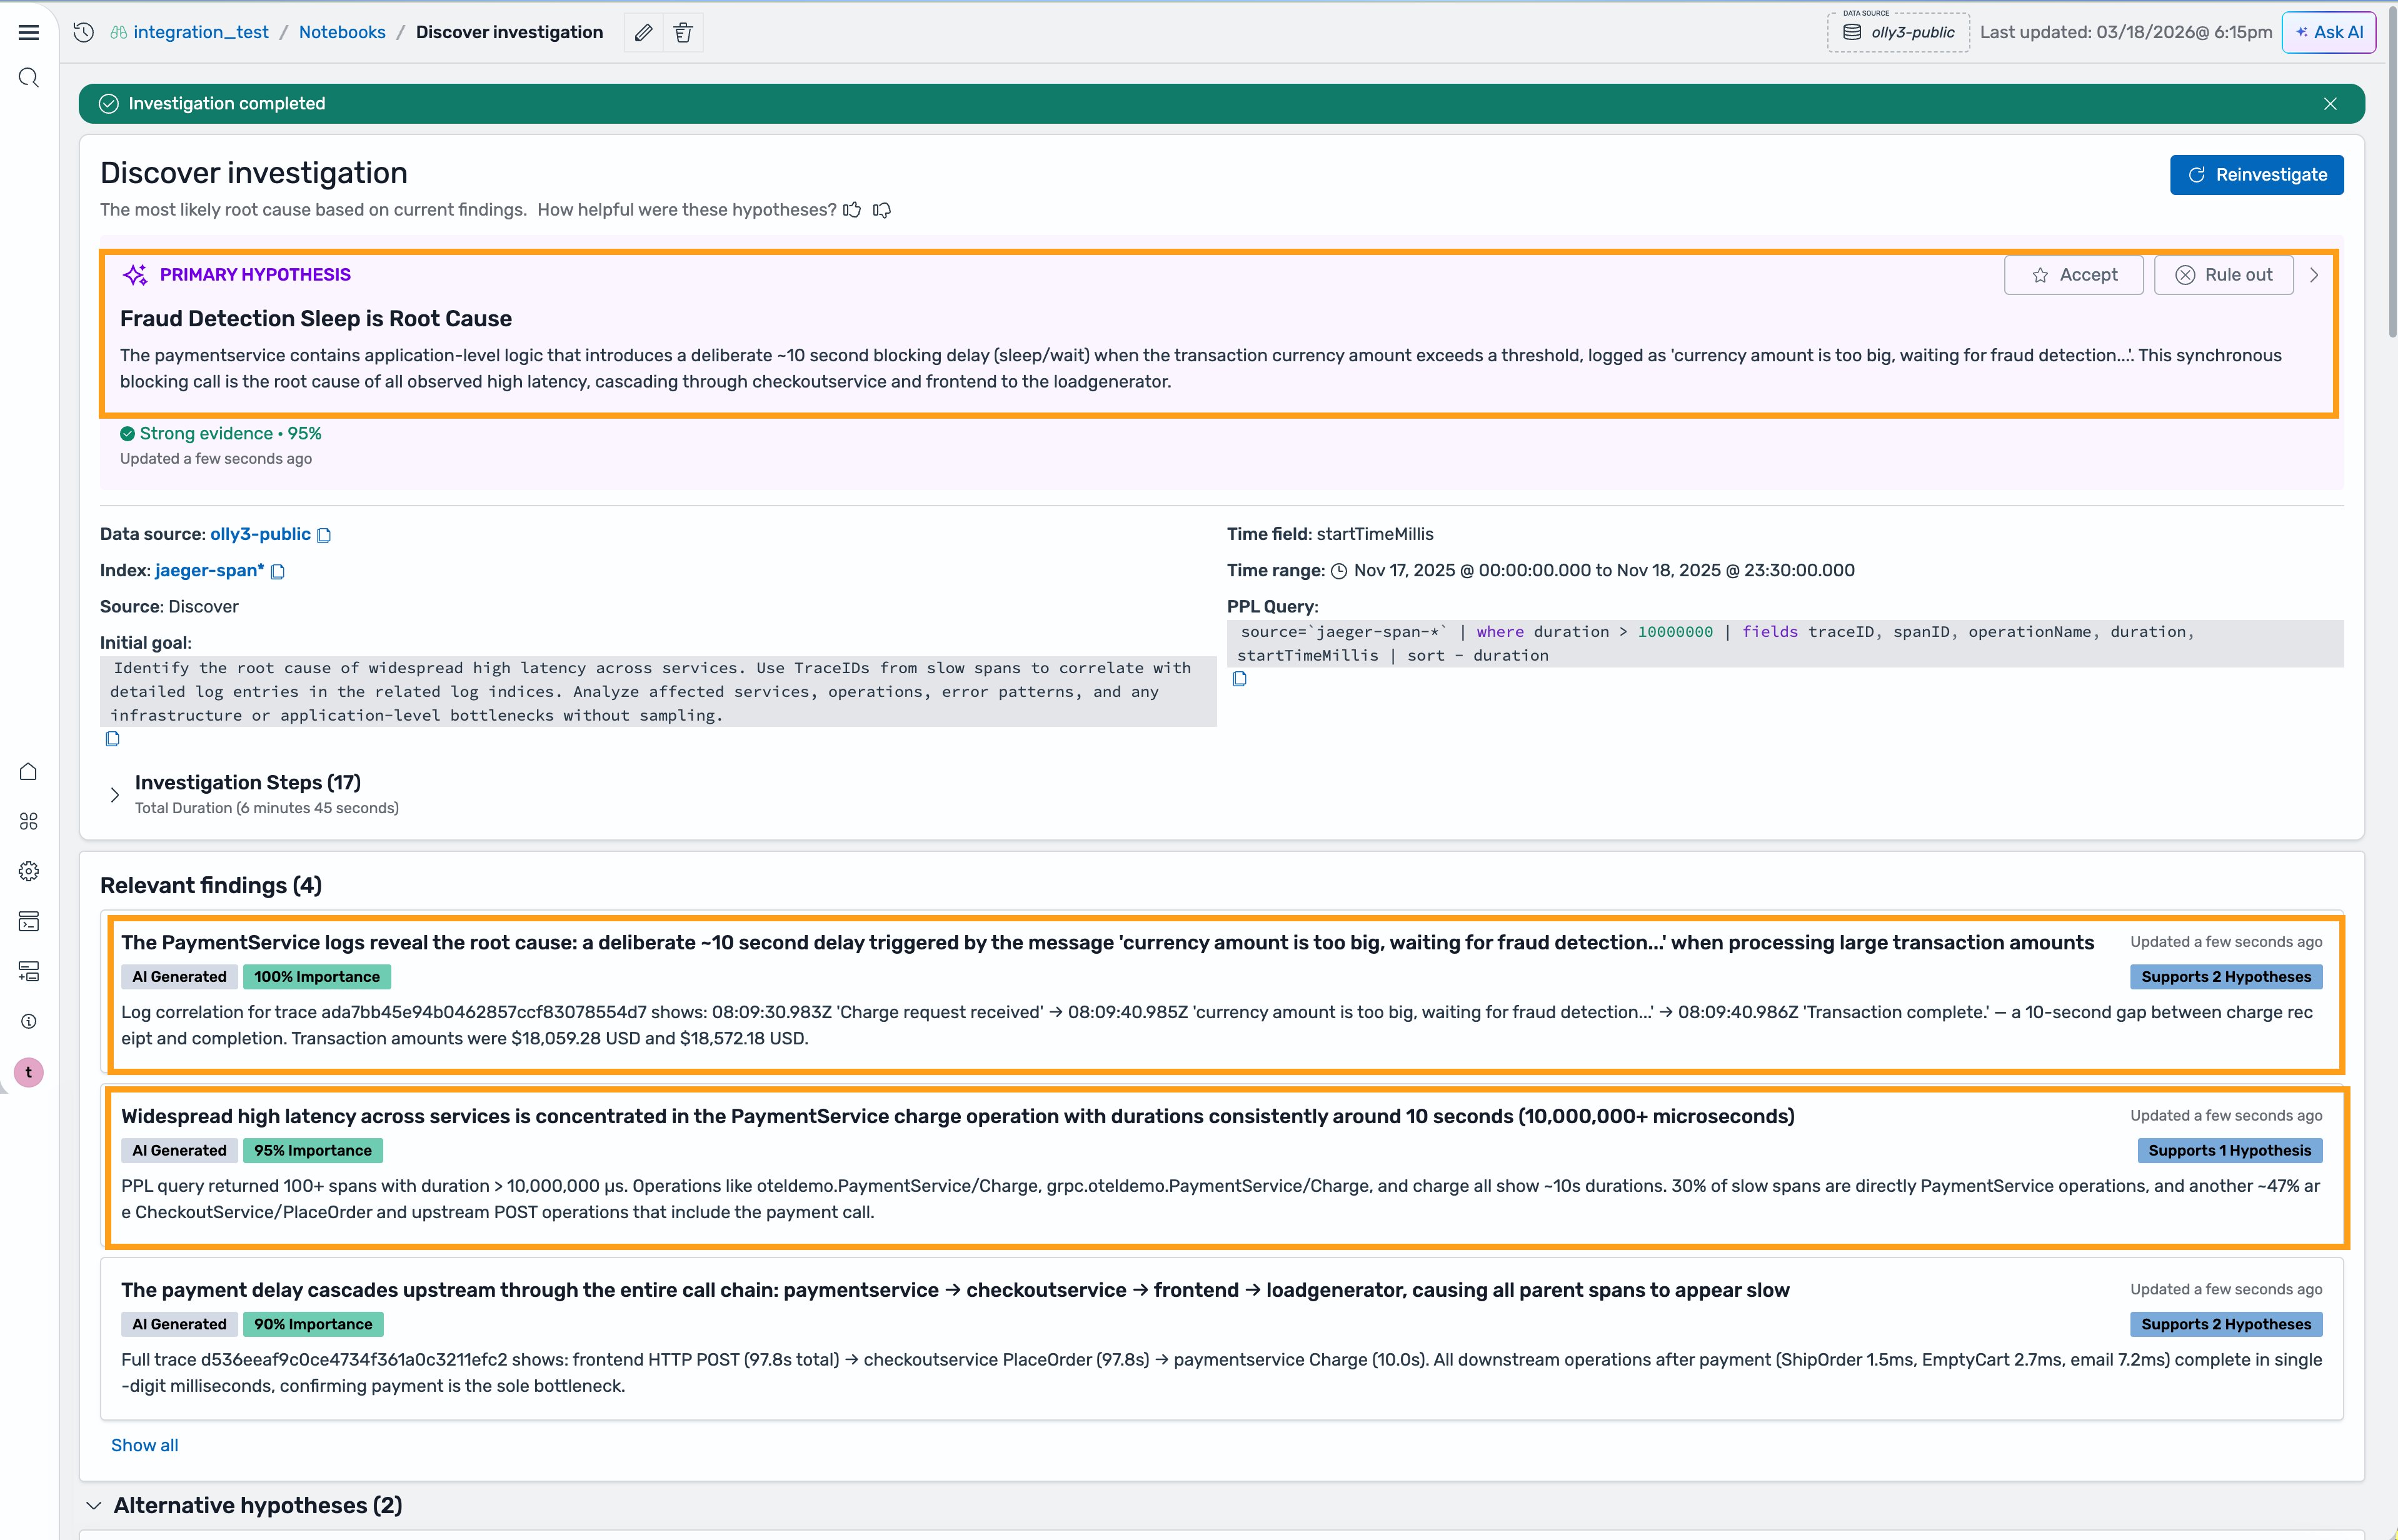
As the investigation completes, the investigation agent concludes that the most likely hypothesis is a fraud detection timeout. The associated finding shows a log entry from the payment service: “currency amount is too big, waiting for fraud detection”. This matches a known system design where large transactions trigger a fraud detection call that blocks the request until the transaction is scored and assessed. The agent arrived at this finding by correlating data across two separate indices, a metrics index where the original duration data lived, and a correlated log index where the payment service entries were stored. The agent linked these indices using trace IDs, connecting the latency measurement to the specific log entry that explained it.
After reviewing the hypothesis and the supporting evidence, you find the result reasonable and aligns with your domain knowledge and past experiences with similar issues. You can now accept the hypothesis and review the request flow topology for the affected traces that were provided as part of the hypothesis investigation.
Alternatively, if you find that the initial hypothesis wasn’t helpful, you can review the alternative hypothesis at the bottom of the report and select any of the alternative hypotheses if there’s one that’s more accurate. You can also trigger a re-investigation with additional inputs, or corrections from previous input so that the Investigation Agent can rework it.
Getting started
You can use any of the new agentic AI features (limits apply) in the OpenSearch UI at no cost. You will find the new agentic AI features ready to use in your OpenSearch UI applications, unless you have previously disabled AI features in any OpenSearch Service domains in your account. To enable or disable the AI features, you can navigate to the details page of the OpenSearch UI application in AWS Management Console and update the AI settings from there. Alternatively, you can also use the registerCapability API to enable the AI features or use the deregisterCapability API to disable them. Learn more at Agentic AI in Amazon OpenSearch Services.
The agentic AI feature uses the identity and permissions of the logged in users for authorizing access to the connected data sources. Make sure that your users have the necessary permissions to access the data sources. For more information, see Getting Started with OpenSearch UI.
The investigation results are saved in the metadata system of OpenSearch UI and encrypted with a service managed key. Optionally, you can configure a customer managed key to encrypt all of the metadata with your own key. For more information, see Encryption and Customer Managed Key with OpenSearch UI.
The new agentic AI capabilities announced for Amazon OpenSearch Service help reduce Mean Time to Resolution by providing context-aware agentic chatbot for assistance, hypothesis-driven investigations with full explainability, and agentic memory for context consistency. With the new agentic AI capabilities, your engineering team can spend less time writing queries and correlating signals, and more time acting on confirmed root causes. We invite you to explore these capabilities and experiment with your applications today.
Hello! I’m Daniel Abib, and this is my first AWS Weekly Roundup. I’m a Senior Specialist Solutions Architect at AWS, focused on the generative AI and Amazon Bedrock. With over 28 years of experience in solution architecture, software development, and cloud architecture, I help Startups & Enterprises harness the power of generative AI with Amazon Bedrock. I’ve been at AWS for more than six and a half years, working closely with customers across Latin America, and I’m also passionate about Serverless technologies.
Outside of work and endurance sports, I’m a dedicated father to Cecília (7) and Rafael (4), who keep me busier—and happier— than any distributed system ever could. I’m based in São Paulo, you can find me on LinkedIn and X (@DCABib), where I share insights about generative AI, Amazon Bedrock, AWS serverless services, and the occasional Ironman throwback.
Now, let’s get into this week’s AWS news…
Last week’s launches Here are some launches and updates from this past week that caught my attention:
Amazon Redshift increases performance for new queries in dashboards and ETL workloads by up to 7x — Amazon Redshift now delivers up to 7x faster performance for new queries in dashboards and ETL workloads. Queries you run for the first time — without cached results — now execute significantly faster, reducing wait times for interactive dashboards and accelerating your ETL pipelines. This is particularly impactful for workloads with high query variability where cache hits are less frequent.
NVIDIA Nemotron 3 Super now available on Amazon Bedrock — NVIDIA Nemotron 3 Super is now available in Amazon Bedrock, expanding the lineup of foundation models you can access through the unified Bedrock API. Nemotron 3 Super is a high-performance language model optimized for tasks such as text generation, complex reasoning, summarization, and code generation. You can now invoke Nemotron 3 Super alongside other foundation models in your existing Bedrock workflows, without managing any infrastructure.
Introducing Nova Forge SDK, a seamless way to customize Nova models for enterprise AI — Nova Forge SDK provides a streamlined way to fine-tune and customize Amazon Nova models for enterprise use cases. You can adapt Nova models to your domain-specific data and deploy them directly within Amazon Bedrock, reducing the complexity of building tailored AI solutions. The SDK handles the heavy lifting of model customization, letting you focus on your business logic rather than the underlying infrastructure.
Amazon Corretto 26 is now generally available — Amazon Corretto 26, the latest long-term support (LTS) release of the no-cost, production-ready distribution of OpenJDK, is now generally available. Corretto 26 includes the latest Java language features, performance improvements, and security patches, all backed by long-term support from AWS. You can use it across development and production environments on Amazon Linux, Windows, macOS, and Docker images.
AWS Lambda now supports Availability Zone metadata — AWS Lambda now provides Availability Zone metadata for your function invocations. You can now identify which Availability Zone your Lambda function is running in, enabling better observability, more informed architectural decisions, and simplified troubleshooting for latency-sensitive and multi-AZ workloads. This is particularly useful when correlating Lambda execution with other AZ-aware services in your architecture.
Amazon CloudWatch Logs now supports log ingestion using HTTP-based protocol — Amazon CloudWatch Logs now supports ingesting logs using an HTTP-based protocol, making it simpler to send logs from applications and services that use standard HTTP endpoints. You can now route logs to CloudWatch Logs without requiring custom agents or additional SDK integrations, lowering the barrier to centralized log management across your workloads.
Amazon EKS announces 99.99% Service Level Agreement and new 8XL scaling tier for Provisioned Control Plane clusters — Amazon EKS now offers a 99.99% Service Level Agreement (SLA) for clusters running on Provisioned Control Plane, up from the 99.95% SLA offered on standard control plane. EKS is also introducing the 8XL scaling tier, the largest available Provisioned Control Plane tier, which doubles the Kubernetes API server request processing capacity of the next lower 4XL tier — ideal for large-scale workloads like AI/ML training, high-performance computing (HPC), and large-scale data processing.
Other AWS news Here are some additional posts and resources that you might find interesting:
Kiro for students — Kiro is now available for students, giving the next generation of builders access to AI-powered development tools at no cost. As Swami Sivasubramanian shared on LinkedIn, “Students are the future decision-makers shaping technology” — and Kiro gives them hands-on experience building with AI from day one. If you’re a student or know someone who is, this is a great opportunity to start building with AI-assisted development.
Strands Steering Hooks achieved 100% agent accuracy — The Strands Agents team published results showing that Steering Hooks can achieve 100% agent accuracy, outperforming both prompt engineering and rigid workflow approaches for controlling agent behavior. As Swami highlighted on LinkedIn, building reliable AI agents often means rethinking how we guide model behavior — and Steering Hooks offer a compelling new path to agent reliability.
Introducing Badges on AWS Builder Center — AWS Builder Center now features badges that recognize your contributions and achievements within the builder community. You can earn badges by sharing solutions, participating in challenges, and engaging with fellow builders. It’s a great way to showcase your expertise and track your growth.
Keep Building Together: The Power of Community — A thoughtful read on the power of community-driven learning and collaboration in the AWS ecosystem. Whether you’re just getting started with AWS or you’ve been building for years, the builder community is a place to connect, share knowledge, and grow together. I highly recommend checking it out.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
AWS Summits — Join AWS Summits in 2026, free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), Bengaluru (April 23–24), Singapore (May 6), Tel Aviv (May 6), and Stockholm (May 7).
AWS Community Days — Community-led conferences where content is planned, sourced, and delivered by community leaders, featuring technical discussions, workshops, and hands-on labs. Upcoming events include San Francisco (April 10) and Romania (April 23–24).
AWSome Women Summit LATAM — Taking place on March 28 in Mexico City, this event celebrates and empowers women in cloud technology across Latin America. A fantastic initiative for the LATAM tech community.
Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse the AWS Events and Webinars for upcoming AWS-led in-person and virtual events and developer-focused events.
That’s all for this week. Check back next Monday for another Weekly Roundup!
This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!
Twenty years ago this past week, Amazon S3 launched publicly on March 14, 2006. While Amazon Simple Storage Service is often considered the foundational storage service that defined cloud infrastructure, what began as a simple object storage service has grown into something far larger in scope and scale.
As of March 2026, S3 stores more than 500 trillion objects, serves more than 200 million requests per second globally across hundreds of exabytes of data, and the price has dropped to just over 2 cents per gigabyte — an approximately 85% reduction since launch. My colleague Sébastien Stormacq wrote a detailed look at the engineering and the road ahead in Twenty years of Amazon S3 and building what’s next, and if you want to read about those earliest customers and how they shaped what AWS became, I recommend How three startups helped Amazon invent cloud computing and paved the way for AI. Twenty years is worth pausing to celebrate.
Alongside the 20th anniversary of S3, Channy Yun also wrote about a new S3 feature this week: Account regional namespaces for Amazon S3 general purpose buckets. With this feature, you can create general purpose buckets in your own account regional namespace by appending your account’s unique suffix to your requested bucket name, ensuring your desired names are always reserved exclusively for your account. You can enforce adoption across your organization using AWS IAM policies and AWS Organizations service control policies with the new s3:x-amz-bucket-namespace condition key. Read Channy’s post to learn more about account regional namespaces for Amazon S3 general purpose buckets.
This week’s featured launch is one I have a personal connection to: the general availability of Amazon Route 53 Global Resolver. I wrote about the preview of this capability back in December at re:Invent 2025, and I had a great time putting that post together, so I am happy to hear that it’s generally available now.
Amazon Route 53 Global Resolver is an internet-reachable anycast DNS resolver that provides DNS resolution for authorized clients from any location. It is now generally available across 30 AWS Regions, with support for both IPv4 and IPv6 DNS query traffic. Route 53 Global Resolver gives authorized clients in your organization anycast DNS resolution of public internet domains and private domains associated with Route 53 private hosted zones — from any location, not just from within a specific VPC or Region. It also provides DNS query filtering to block potentially malicious domains, domains that are not safe for work, and domains associated with advanced DNS threats such as DNS tunneling and Domain Generation Algorithms (DGA). Centralized query logging is included as well. With general availability, Global Resolver adds protection against Dictionary DGA threats.
Last week’s launches Here are some of the other announcements from last week:
Amazon Bedrock AgentCore Runtime now supports stateful MCP server features — Amazon Bedrock AgentCore Runtime now supports stateful Model Context Protocol (MCP) server features, enabling developers to build MCP servers that use elicitation, sampling, and progress notifications alongside existing support for resources, prompts, and tools. With stateful MCP sessions, each user session runs in a dedicated microVM with isolated resources, and the server maintains session context across multiple interactions using an Mcp-Session-Id header. Elicitation enables server-initiated, multi-turn conversations to gather structured input from users during tool execution. Sampling allows servers to request LLM-generated content from the client for tasks such as personalized recommendations. Progress notifications keep clients informed during long-running operations. To learn more, see the Amazon Bedrock AgentCore documentation.
Amazon WorkSpaces now supports Microsoft Windows Server 2025 — New bundles powered by Microsoft Windows Server 2025 are now available for Amazon WorkSpaces Personal and Amazon WorkSpaces Core. These bundles include security capabilities such as Trusted Platform Module 2.0 (TPM 2.0), Unified Extensible Firmware Interface (UEFI) Secure Boot, Secured-core server, Credential Guard, Hypervisor-protected Code Integrity (HVCI), and DNS-over-HTTPS. Existing Windows Server 2016, 2019, and 2022 bundles remain available. You can use the managed Windows Server 2025 bundles or create a custom bundle and image. This support is available in all AWS Regions where Amazon WorkSpaces is available. For more information, visit the Amazon WorkSpaces FAQs.
AWS Builder ID now supports Sign in with GitHub and Amazon — AWS Builder ID now supports two additional social login options: GitHub and Amazon. These options join the existing Google and Apple sign-in capabilities. With this update, developers can access their AWS Builder ID profile — and services including AWS Builder Center, AWS Training and Certification, and Kiro — using their existing GitHub or Amazon account credentials, without managing a separate set of credentials. To learn more and get started, visit the AWS Builder ID documentation.
Amazon Redshift introduces reusable templates for COPY operations — Amazon Redshift now supports templates for the COPY command, allowing you to store and reuse frequently used COPY parameters. Templates help maintain consistency across data ingestion operations, reduce the effort required to execute COPY commands, and simplify maintenance by applying template updates automatically to all future uses. Support for COPY templates is available in all AWS Regions where Amazon Redshift is available, including the AWS GovCloud (US) Regions. To get started, see the documentation or read the Standardize Amazon Redshift operations using Templates blog.
For a full list of AWS announcements, be sure to keep an eye on our News Blog channel the What’s New with AWS page.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
AWS Summits – Join AWS Summits in 2026, free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).
AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders, featuring technical discussions, workshops, and hands-on labs. Upcoming events include Pune (March 21), San Francisco (April 10), and Romania (April 23-24).
AWS at NVIDIA GTC 2026 — Join us at our AWS sessions, booths, demos, and ancillary events in NVIDIA GTC 2026 on March 16 – 19, 2026 in San Jose. You can receive 20% off event passes through AWS and request a 1:1 meeting at GTC.
AWS Community GameDay Europe — Taking place on March 17, 2026, AWS Community GameDay Europe is a team-based, hands-on AWS challenge event running simultaneously across 50+ cities in Europe. Your team is dropped into a broken AWS environment — misconfigured services, failing architectures, and security gaps — and has two hours to fix as much as possible. Find your nearest city and sign up at awsgameday.eu.
Last week was an incredible whirlwind: a round of meetups, hands-on workshops, and career discussions across Kenya that culminated with the AWS Student Community Day at Meru University of Science and Technology, with keynotes from my colleagues Veliswa and Tiffany, and sessions on everything from GitOps to cloud-native engineering, and a whole lot of AI agent building.
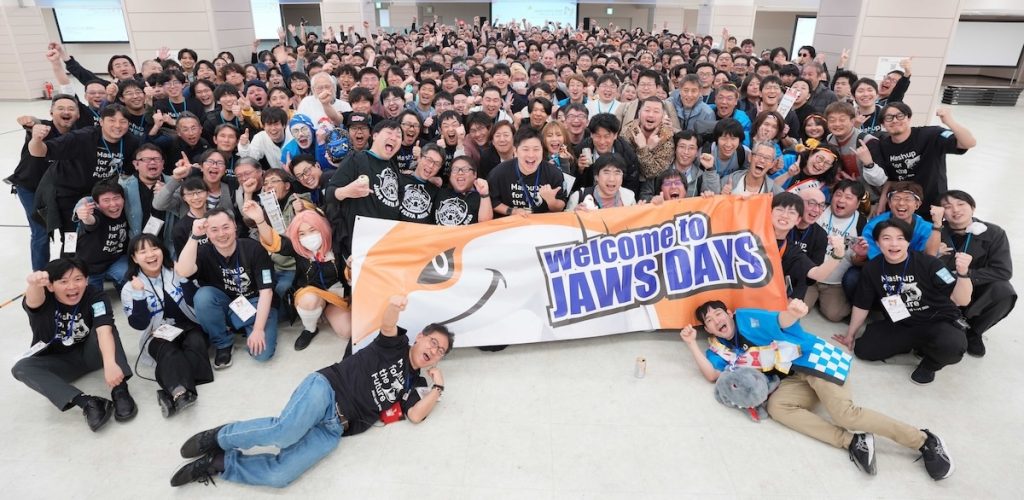
JAWS Days 2026 is the largest AWS Community Day in the world, with over 1,500 attendees on March 7th. This event started with a keynote speech on building an AI-driven development team by Jeff Barr, and included over 100 technical and community experience sessions, lightning talks, and workshops such as Game Days, Builders Card Challenges, and networking parties.
Now, let’s get into this week’s AWS news…
Last week’s launches Here are some launches and updates from this past week that caught my attention:
Introducing Amazon Connect Health, Agentic AI Built for Healthcare — Amazon Connect Health is now generally available with five purpose-built AI agents for healthcare: patient verification, appointment management, patient insights, ambient documentation, and medical coding. All features are HIPAA-eligible and deployable within existing clinical workflows in days.
Policy in Amazon Bedrock AgentCore is now generally available — You can now use centralized, fine-grained controls for agent-tool interactions that operate outside your agent code. Security and compliance teams can define tool access and input validation rules using natural language that automatically converts to Cedar, the AWS open-source policy language.
Introducing OpenClaw on Amazon Lightsail to run your autonomous private AI agents — You can deploy a private AI assistant on your own cloud infrastructure with built-in security controls, sandboxed agent sessions, one-click HTTPS, and device pairing authentication. Amazon Bedrock serves as the default model provider, and you can connect to Slack, Telegram, WhatsApp, and Discord.
AWS announces pricing for VPC Encryption Controls — Starting March 1, 2026, VPC Encryption Controls transitions from free preview to a paid feature. You can audit and enforce encryption-in-transit of all traffic flows within and across VPCs in a region, with monitor mode to detect unencrypted traffic and enforce mode to prevent it.
AWS Elastic Beanstalk now offers AI-powered environment analysis — When your environment health is degraded, Elastic Beanstalk can now collect recent events, instance health, and logs and send them to Amazon Bedrock for analysis, providing step-by-step troubleshooting recommendations tailored to your environment’s current state.
AWS simplifies IAM role creation and setup in service workflows — You can now create and configure IAM roles directly within service workflows through a new in-console panel, without switching to the IAM console. The feature supports Amazon EC2, Lambda, EKS, ECS, Glue, CloudFormation, and more.
Accelerate Lambda durable functions development with new Kiro power — You can now build resilient, long-running multi-step applications and AI workflows faster with AI agent-assisted development in Kiro. The power dynamically loads guidance on replay models, step and wait operations, concurrent execution patterns, error handling, and deployment best practices.
Amazon GameLift Servers launches DDoS Protection — You can now protect session-based multiplayer games against DDoS attacks with a co-located relay network that authenticates client traffic using access tokens and enforces per-player traffic limits, at no additional cost to GameLift Servers customers.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
From AWS community Here are my personal favorite posts from AWS community and my colleagues:
When the Model Is the Machine — Mike Chambers built an experimental app where an AI agent generates a complete, interactive web application at runtime from a single prompt — no codebase, no framework, no persistent state. A thought-provoking exploration of what happens when the model becomes the runtime.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
AWS Community GameDay Europe — Think you know AWS? Prove it at the AWS Community GameDay Europe on March 17, a gamified learning event where teams compete to solve real-world technical challenges using AWS services.
AWS at NVIDIA GTC 2026 — Join us at our AWS sessions, booths, demos, and ancillary events in NVIDIA GTC 2026 on March 16 – 19, 2026 in San Jose. You can receive 20% off event passes through AWS and request a 1:1 meeting at GTC.
AWS Summits — Join AWS Summits in 2026: free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).
AWS Community Days — Community-led conferences where content is planned, sourced, and delivered by community leaders. Upcoming events include Slovakia (March 11), Pune (March 21), and the AWSome Women Summit LATAM in Mexico City (March 28)
This improvement addresses a challenge in technical support workflow: when a support engineer receives a new customer case, the biggest bottleneck is often not diagnosing the problem but preparing the data. Customer logs arrive in different formats from multiple vendors, and each new log format typically requires manual integration and correlation before an investigation can begin. For simple cases, this process can take hours. For more complex investigations, it can take days, slowing resolution and reducing overall engineer productivity.
CyberArk is a global leader in identity security. Centered on intelligent privilege controls, it provides comprehensive security for human, machine, and AI identities across business applications, distributed workforces, and hybrid cloud environments.
In this post, we show you how CyberArk redesigned their support operations by combining Iceberg’s intelligent metadata management with AI-powered automation from Amazon Bedrock. You’ll learn how to simplify data processing flows, automate log parsing for diverse formats, and build autonomous investigation workflows that scale automatically.
To achieve these results, CyberArk needed a solution that could ingest customer logs, automatically structure them, establish relationships between related events, and make everything queryable in minutes, not days. The architecture had to be serverless to handle unpredictable support volumes, secure enough to protect customer Personally Identifiable Information (PII), and fast enough to allow same day case resolution.
The legacy architecture: Bottlenecks and manual workflows
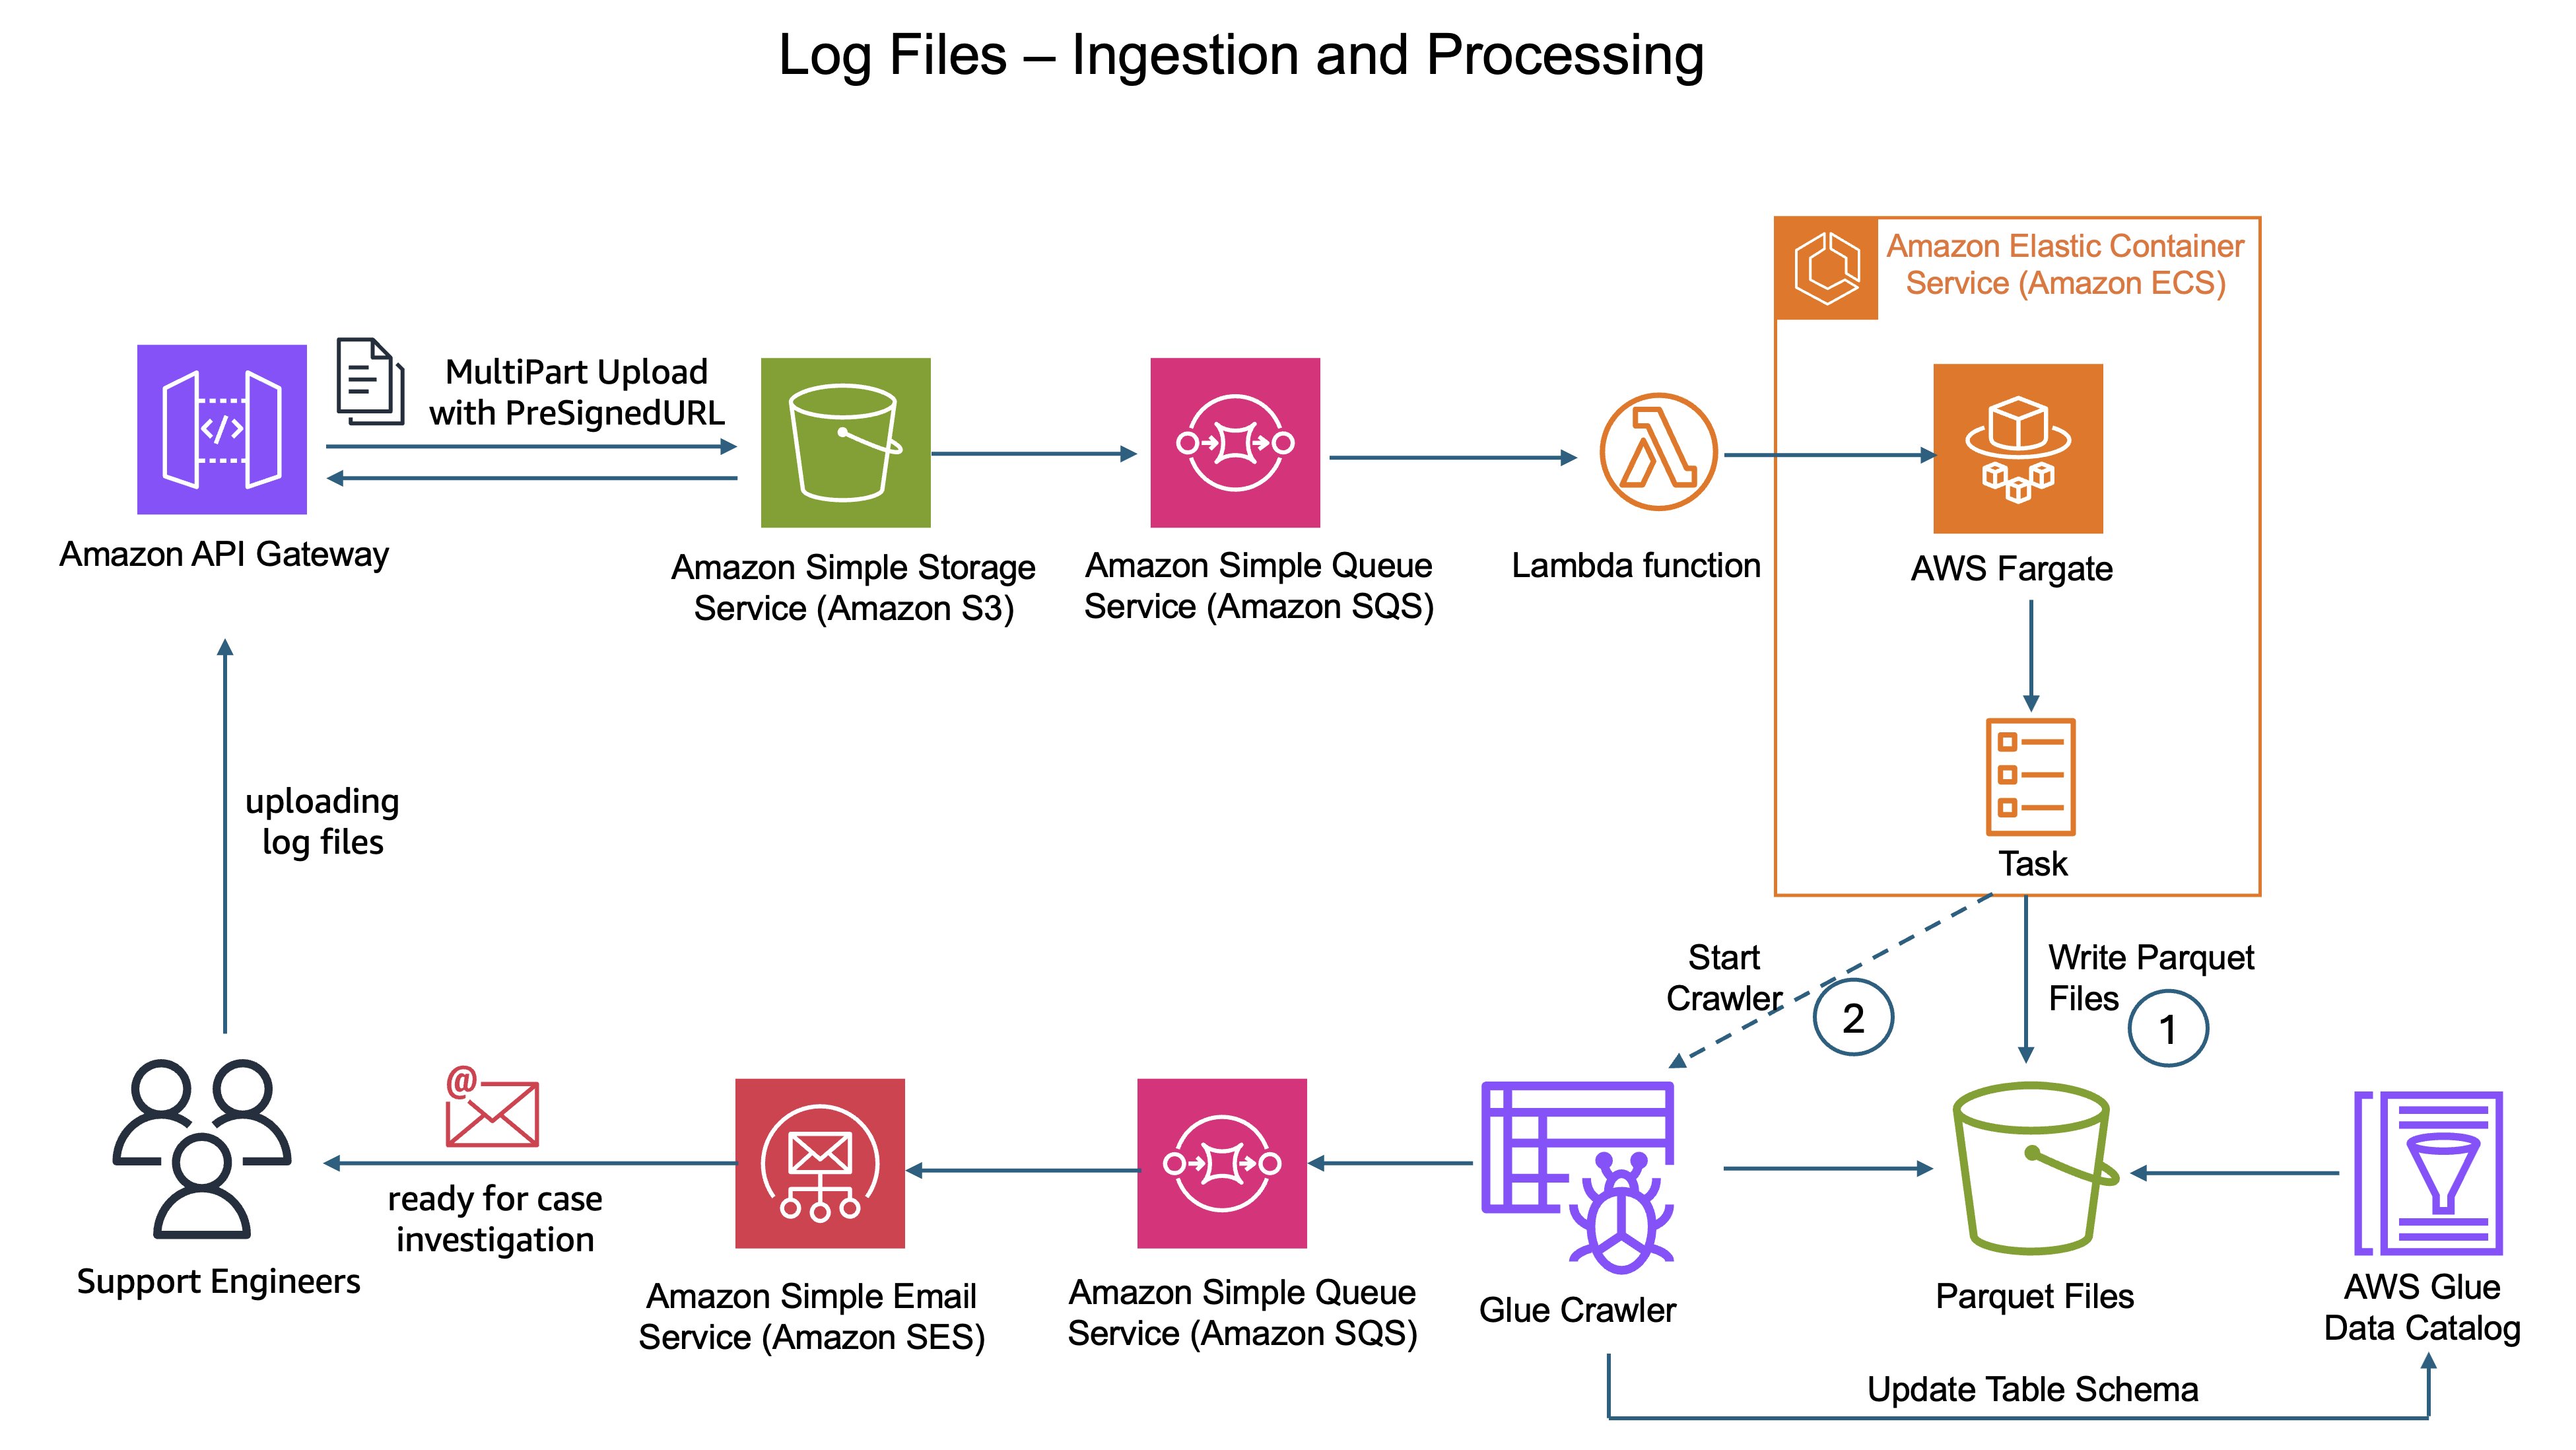
When support engineers received customer cases, they would upload log files to the data lake stored in Amazon Simple Storage Service (Amazon S3). The original design then suffered from the complexity of multi-step raw data processing.
First, CyberArk’s custom parsing logic running on AWS Fargate would parse these uploaded log files and transform the raw data. During this stage, the system also had to scan for PII and mask sensitive data to protect customer privacy.
Next, a separate process converted the processed data into Parquet format.
Finally, AWS Glue crawlers were required to discover new partitions and update table metadata for processed Parquet files. This dependency became the most complex and time-consuming part of the pipeline. Crawlers ran as asynchronous batch jobs rather than in real time, often introducing delays of minutes to hours before support engineers could query the data.
But the inefficiency went deeper than just architectural complexity. CyberArk supports customers running diverse product environments across multiple vendors. Each vendor and product produces logs in different formats with unique schemas, field names, and structures. Adding support for a new vendor meant days of integration work to understand their log format and build custom parsers.
Figure 1: Legacy log ingestion architecture diagram showing the flow from S3 upload through AWS Fargate processing with AWS Glue Crawler
Beyond ingestion, the investigation process itself was manual and time consuming. Support engineers would manually query data, correlate events across different log sources, search through product documentation, and piece together root cause analysis through trial and error. This process required deep product expertise and could take hours or days depending on issue complexity. The new architecture addresses these inefficiencies through three key innovations:
Single stage serverless processing: AWS Fargate with PyIceberg directly creates Iceberg tables from raw logs in one pass, removing intermediate processing steps and crawler dependencies entirely.
AI powered dynamic parsing: Amazon Bedrock automatically generates grok patterns for log parsing by analyzing file schemas, transforming what was once a manual, time consuming process into a fully automated workflow.
Autonomous investigation with AI Agents: AI Agents autonomously perform complete root cause analysis by querying log data, analyzing product knowledge bases, identifying event flows, and recommending solutions, transforming hours of manual investigation into minutes of automated intelligence.
The solution: AI-powered automation meets single-stage Iceberg processing
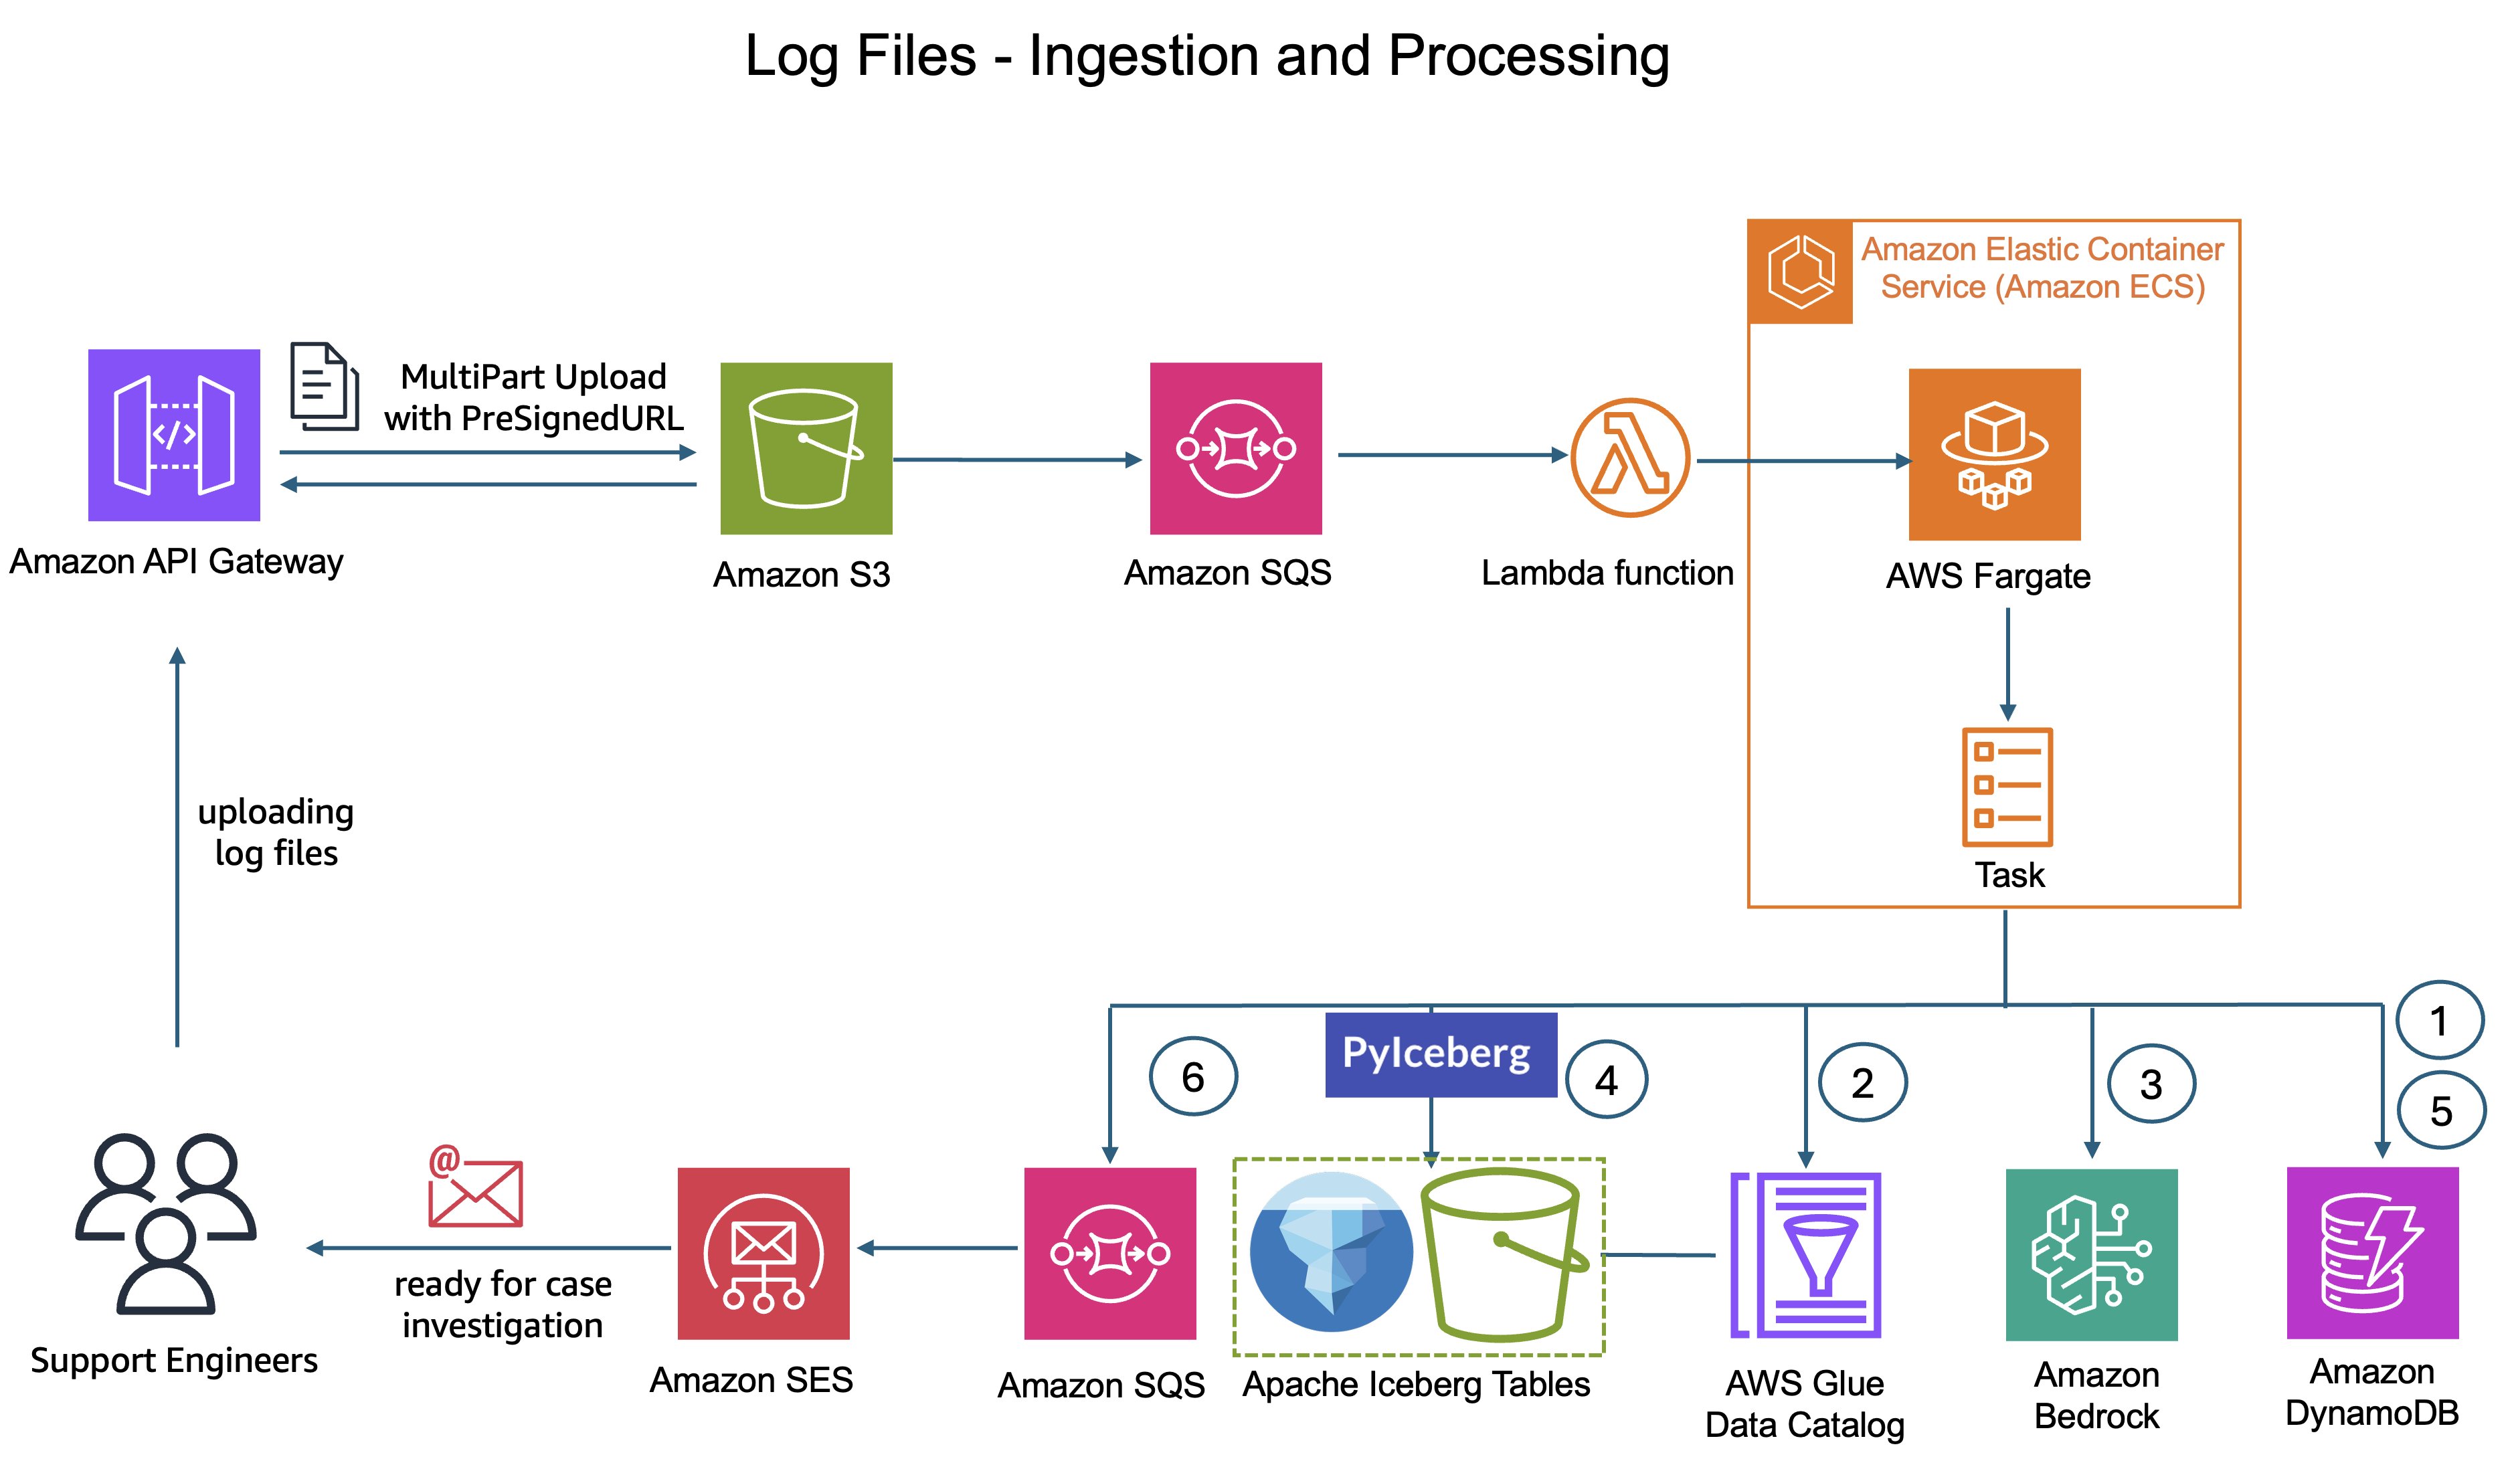
The new system delivers zero touch log processing from upload to query. Support engineers simply upload customer log ZIP files to the system. Here’s where the transformation happens: CyberArk’s custom processing logic still runs on AWS Fargate, but now it uses Amazon Bedrock to intelligently understand the data.
Zero-touch log processing workflow
The system extracts sample log entries from the uploaded log files and sends them to Amazon Bedrock along with context about the log source and table schema from AWS Glue Data Catalog. Amazon Bedrock analyzes the samples, understands the structure, and automatically generates grok patterns optimized for the specific log format.
Grok patterns are structured expressions that define how to extract meaningful fields from unstructured log text. For example, the following grok pattern specifies that a timestamp appears first, followed by a severity level, then a message body %{TIMESTAMP_ISO8601:timestamp} %{LOGLEVEL:severity} %{GREEDYDATA:message}
The system validates these grok patterns against additional samples to verify accuracy before applying them to parse the complete log file. Successfully validated grok patterns are stored in Amazon DynamoDB, creating a repository of known patterns. When the system encounters similar log formats in future uploads, it can retrieve these patterns directly from Amazon DynamoDB, avoiding redundant grok pattern generation. Amazon Bedrock processes log samples in real-time without retaining customer data or using it for model training, maintaining data privacy.
This entire process invokes Claude 3.7 Sonnet model from Amazon Bedrock and is orchestrated by AWS Fargate tasks with retry logic for reliability. The processing uses these AI-generated grok patterns to parse the logs and create or update Iceberg tables using PyIceberg APIs without human intervention.
This automation reduced logs onboarding time from days to minutes, enabling CyberArk to handle diverse customer environments without manual intervention.
Figure 2: Log ingestion architecture diagram showing the flow from S3 upload through AWS Fargate processing with Amazon Bedrock integration to Iceberg table creation
Iceberg simplified and improved CyberArk’s data lake architecture by addressing the two primary bottlenecks in the legacy system: slow schema management and inefficient query performance.
In the legacy architecture, AWS Glue crawlers became a source of operational overhead and latency. Even when triggered on demand, crawlers ran as batch jobs over S3 prefixes to discover partitions and update metadata. As data volumes grew and datasets diversified across vendors and schemas, teams had to manage and operate a growing number of crawler jobs. The resulting delays, often ranging from minutes to hours, slowed data availability and downstream investigation workflows.
Iceberg removes this entire layer of complexity. Iceberg’s intelligent metadata layer automatically tracks table structure, schema changes, and partition information as data is written. When CyberArk’s processing creates or updates Iceberg tables through PyIceberg, the metadata is updated instantly and atomically. There’s no waiting for crawlers jobs to complete, and no risk of stale metadata. The moment data is written, it’s immediately queryable in Amazon Athena.
PyIceberg: Making Iceberg accessible beyond Apache Spark
Working with Iceberg usually involved Apache Spark and the complexity of distributed data processing. PyIceberg changed that by letting CyberArk create and manage Iceberg tables using a simple Python library. CyberArk’s data engineers could write straightforward Python code running on AWS Fargate to create Iceberg tables directly from parsed logs, without spinning up Spark clusters.
This accessibility was essential for CyberArk’s serverless architecture. PyIceberg enabled single stage processing where AWS Fargate tasks could parse logs, apply PII masking, and create Iceberg tables in one pass. The result was simpler code and lower operational overhead.
Metadata-driven query optimization delivers speed
In addition to removing crawlers, Iceberg significantly improved query performance through its intelligent metadata architecture. Iceberg maintains detailed statistics about data files, including min/max values, null counts, and partition information. When support engineers query data in Athena, Iceberg’s metadata layer supports partition pruning and file skipping, making sure queries only read the specific files containing relevant data. For CyberArk’s use case, where tables are partitioned by case ID, this means a query for a specific support case only reads the files for that case, ignoring potentially thousands of irrelevant files. This metadata driven optimization reduced query execution time from minutes to seconds, allowing support engineers to interactively explore data rather than waiting for results.
ACID transactions maintain data consistency
In a multi user support environment where multiple engineers may be analyzing overlapping cases or uploading logs simultaneously, data consistency is essential. Iceberg’s ACID transaction support helps verify that concurrent writes do not corrupt data or create inconsistent states. Each table update is atomic, isolated, and durable, providing the reliability CyberArk needed for production support operations.
Time travel enables historical analysis
Iceberg’s built-in versioning allows support engineers to query historical states of data, essential for understanding how customer issues evolved over time. If an engineer needs to see what the logs looked like when a case was first opened versus after a customer applied a patch, Iceberg’s time travel capabilities make this straightforward. This feature proved essential for complex troubleshooting scenarios where understanding the timeline of events was critical to resolution.
Automated table optimization with AWS Glue
Iceberg tables require periodic maintenance to maintain query performance.
CyberArk enabled AWS Glue automatic table optimization for their Iceberg tables, which handles compaction and expired snapshot cleanup in the background.
For CyberArk’s continuous upload workflow, this automation avoids performance degradation over time. Tables stay optimized without manual intervention from the engineering team.
AI Agents: Autonomous investigation workflow
While the Claude 3.7 Sonnet model from Amazon Bedrock automates grok pattern generation for log ingestion, the more advanced use of Amazon Bedrock comes in the investigation workflow. We use AI agents with Bedrock models to change how support engineers analyze and resolve customer issues.
From manual analysis to AI powered investigation
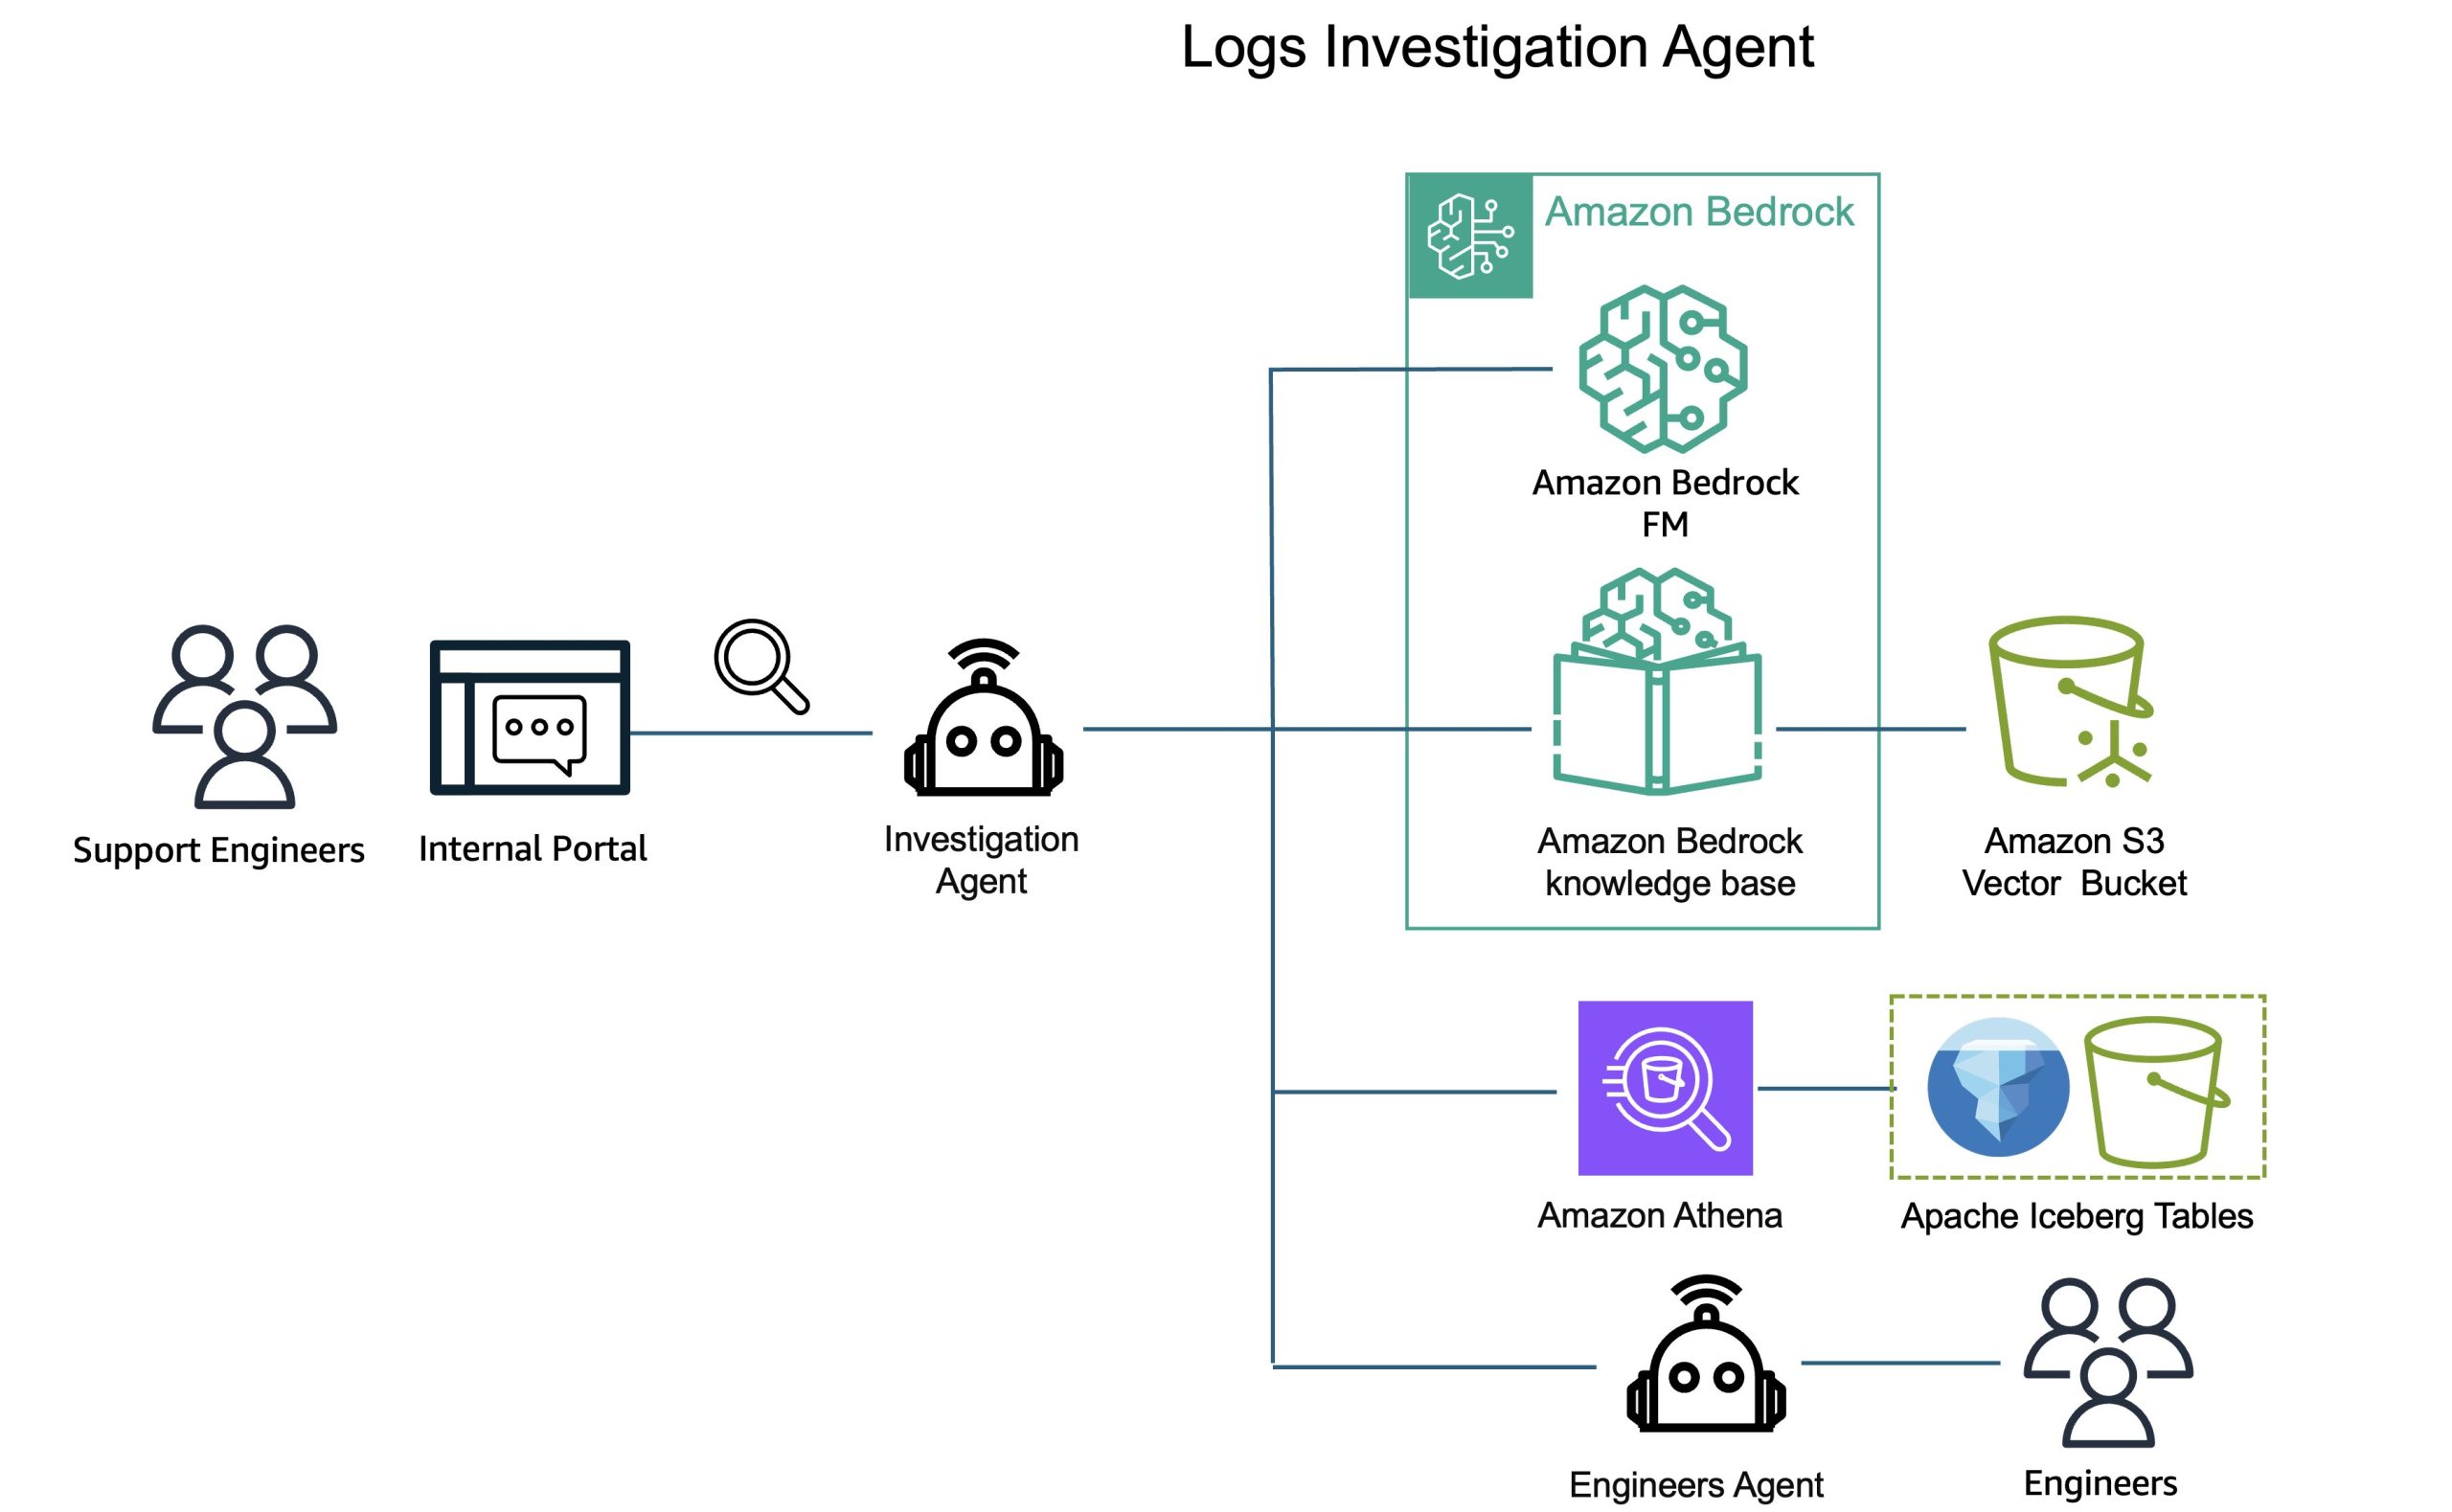
In the legacy workflow, support engineers would manually query data, correlate events across different log sources, search through product documentation, and piece together root cause analysis through trial and error. This process required deep product expertise and could take hours or days depending on issue complexity. AI Agents automate this entire investigation process. Support engineers use an internal portal to ask questions in natural language about customer issues, questions like “Show me authentication errors for case 12345 in the last 24 hours”, “What were the most common errors across cases opened this week?” or “Compare the error patterns between case 12345 and case 12346.”
Behind the scenes, the system fires specialized AI Agents that autonomously perform thorough analysis.
How support agents work
Each AI Agent operates as an intelligent investigator with a clear mission: understand what happened, determine why it happened, and recommend how to fix it. When a support engineer asks a question, the agent collects relevant data by querying Athena to retrieve log data from Iceberg tables, filtering for the specific case and time period relevant to the investigation. The agent then accesses CyberArk’s internal knowledge base for the specific product involved, understanding known issues, common error patterns, and documented solutions. The agent then performs the following analysis:
Flow identification: Analyzes the sequence of events in the logs to understand what actually happened during the customer’s issue
Root cause determination: Correlates log events with product knowledge to identify the underlying cause of the problem
Solution recommendations: Suggests specific remediation steps based on the root cause analysis and known resolution patterns
This entire process happens in minutes, delivering advanced analysis that would have taken support engineers hours to perform manually.
For complex cases where a solution is not found, the support agent escalates to another, specialized agent that interacts with service engineers to collect additional inputs and expertise. This human-in-the-loop approach makes sure that even the most challenging cases receive appropriate attention while still benefiting from the automated investigation workflow. The insights gathered from these escalated cases are automatically fed back into CyberArk’s knowledge base, continuously improving the system’s ability to handle similar issues autonomously in the future.
Amazon Bedrock never shares customer data with model providers or uses it to train foundation models, case data and investigation insights remain within CyberArk’s environment.
Concurrent agent execution at scale
When multiple support engineers investigate different cases simultaneously, the solution runs specialized agents concurrently. CyberArk currently uses Claude 3.7 Sonnet as the foundation model for these agents. Each agent works independently on its assigned investigation, operating in parallel without resource contention. This concurrent execution allows the investigation workflow to scale automatically with support volume, handling peak loads without performance degradation.
AI-powered investigation advantage
This AI-powered investigation workflow delivers two key advantages.
Investigations that took hours now complete in minutes, enabling support engineers to resolve up to 4x more cases per day.
The system also creates a continuous learning feedback loop. When cases require manual resolution by engineers, these resolutions are automatically recorded and fed back into the knowledge base. Future investigations benefit from this accumulated expertise, with agents applying lessons learned from previous manual resolutions to similar cases. Amazon Bedrock doesn’t use customer data to train foundation models. Case data and investigation insights remain within CyberArk’s environment. This automated feedback mechanism means the investigation workflow becomes more effective over time, continuously improving resolution accuracy and speed.
Figure 3: Investigation workflow diagram showing natural language query through AI Agents to Athena queries and knowledge base analysis
Scaling without proportional engineering growth
The business impact of this AI automation is significant. CyberArk can expand its vendor coverage and product portfolio without adding data engineering headcount. The same system that handles today’s log types will automatically handle tomorrow’s additions, whether that’s ten new formats or thousands, significantly reducing time to market for new product and vendor integrations.
The results: Significant improvements in resolution time and productivity
The transformation delivered measurable improvements across every key metric.
Resolution time: CyberArk achieved up to 95% reduction in time from case assignment to resolution. Simple cases that used to take 4 to 6 hours now take just 15 to 30 minutes. Complex cases that previously took up to 15 days are now completed in 2 to 4 hours.
Engineer productivity: Support engineers now handle 8 to 12 cases per day, compared to just 2 to 3 cases before. This means each engineer is helping up to 4x more customers.
Data availability: Logs are queryable within minutes of upload instead of waiting hours or days. Support engineers can start investigating issues almost immediately after receiving customer data.
Operational efficiency: The system requires zero manual intervention for new log formats or schema changes. Cases that used to require days of data engineering work now happen automatically.
Cost optimization: The serverless architecture alleviated idle infrastructure costs while scaling automatically with demand. CyberArk only pays for what they use, when they use it.
Customer satisfaction: Faster resolution times and proactive issue identification significantly improved the customer experience. Problems get solved in hours instead of days, and customers spend less time waiting for answers.
What’s next?
While AWS continues to innovate across both data lake management and agentic AI infrastructure, the following capabilities align well with CyberArk’s architecture and may offer additional operational benefits as the system scale.
Agent infrastructure maturity
As the agent-based architecture scales to handle thousands of concurrent investigations, CyberArk is transitioning to Amazon Bedrock AgentCore for future agent deployments. AgentCore provides a managed runtime for production AI agents with enhanced observability through AWS X-Ray integration, intelligent memory for context retention across sessions, and streamlined operational workflows. While the current AI Agents implementation delivers the performance and reliability CyberArk needs today, AgentCore represents a natural evolution path as operational requirements grow, offering framework-agnostic deployment, automatic scaling, and comprehensive monitoring capabilities without infrastructure management overhead.
Amazon S3 Tables
CyberArk’s current architecture uses Iceberg tables stored in Amazon S3 buckets. Amazon S3 Tables offers fully managed Iceberg tables with built-in optimization.
As CyberArk continue to scale with hundreds of Iceberg tables and rapid data growth, CyberArk is exploring a migration to Amazon S3 Tables to further reduce operational overhead.
S3 Tables remove the need to set up and monitor AWS Glue maintenance jobs. It automatically performs maintenance to enhance the performance of Iceberg tables, including unreferenced file removal, file compaction, and snapshot management. Additionally, S3 Tables provides Intelligent-Tiering that automatically moves data between storage classes based on access patterns, optimizing storage costs without manual intervention.
Because S3 Tables uses Iceberg open table format, migration would not require changes to existing Athena queries and PyIceberg code. This flexibility allows CyberArk to evaluate and adopt S3 Tables when the operational and cost benefits align with their business needs.
Conclusion
CyberArk’s transformation demonstrates how combining modern data lake architecture with AI automation can significantly change operational economics. By combining Iceberg’s intelligent metadata management with AI-powered automation from Amazon Bedrock, CyberArk transformed case resolution from days to minutes while enabling support operations to scale automatically with business growth. Support engineers now spend their time solving customer problems instead of wrangling data, customers receive faster resolutions, and the system scales automatically with the business.
Customers of all sizes have been successfully using Amazon OpenSearch Service to power their observability workflows and gain visibility into their applications and infrastructure. During incident investigation, Site Reliability Engineers (SREs) and operations center personnel rely on OpenSearch Service to query logs, examine visualizations, analyze patterns, correlate traces to find the root cause of the incident, and reduce Mean Time to Resolution (MTTR). When an incident happens that triggers alerts, SREs typically jump between multiple dashboards, write specific queries, check recent deployments, and correlate between logs and traces to piece together a timeline of events. Not only is this process largely manual, but it also creates a cognitive load on these personnel, even when all the data is readily available. This is where agentic AI can help, by being an intelligent assistant that can understand how to query, interpret various telemetry signals, and systematically investigate an incident.
In this post, we present an observability agent using OpenSearch Service and Amazon Bedrock AgentCore that can help surface root cause and get insights faster, handle multiple query-correlation cycles, and ultimately reduce MTTR even further.
Solution overview
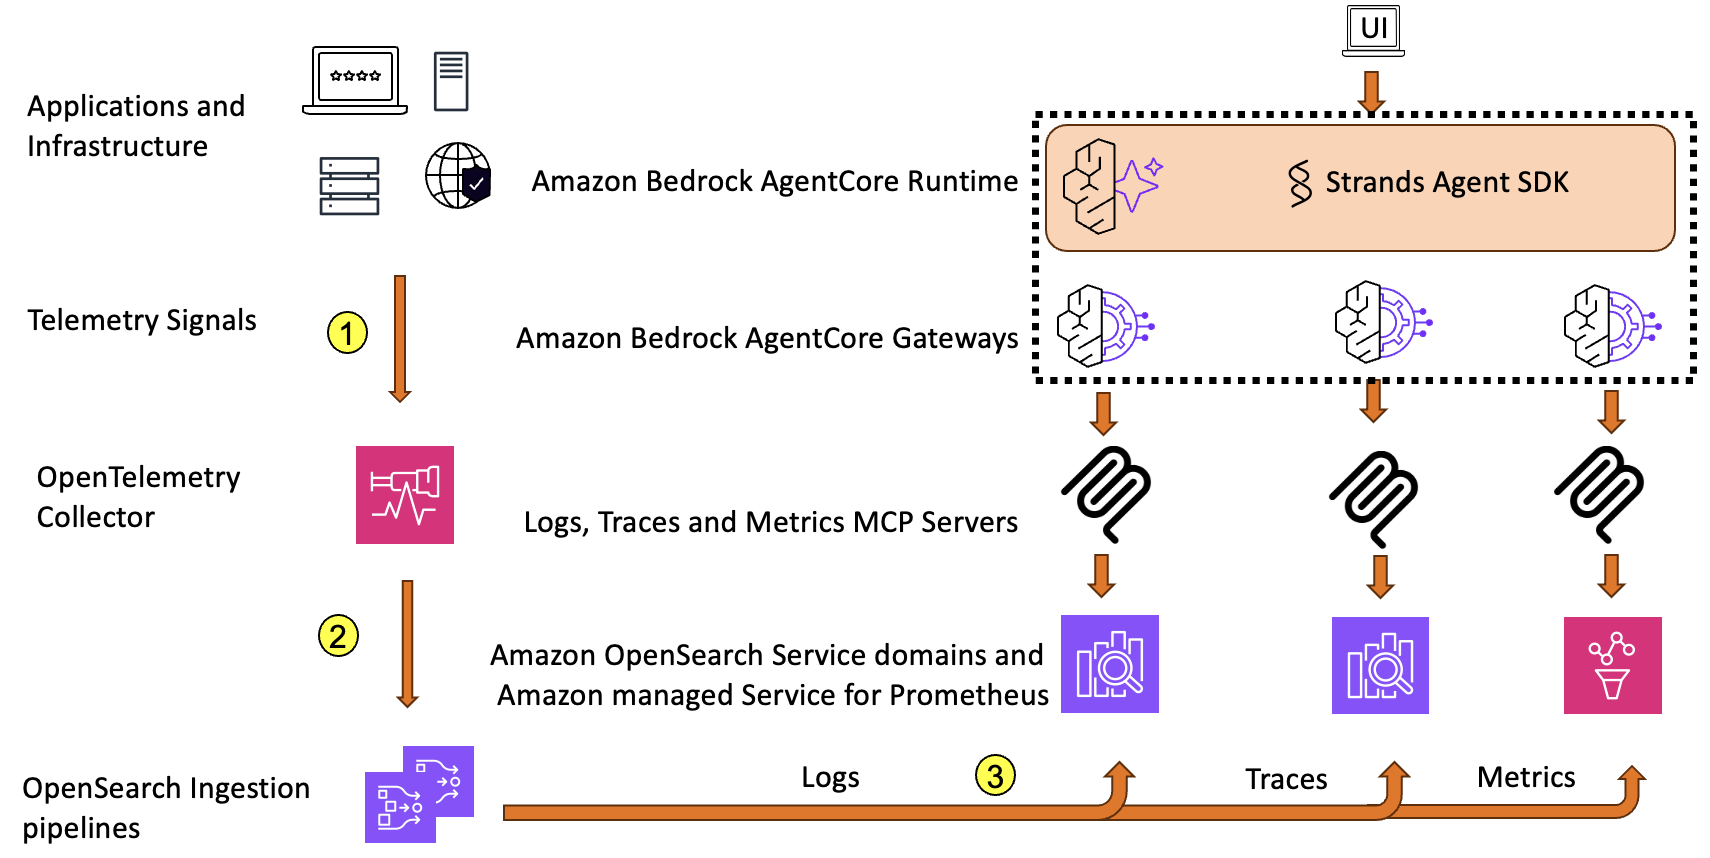
The following diagram shows the overall architecture for the observability agent.
OpenTelemetry is the standard for instrumentation, and provides vendor-neutral data collection across a broad range of languages and frameworks. Enterprises of various sizes are adopting this architecture pattern using OpenTelemetry for their observability needs, especially those committed to open source tools. More notably, this architecture builds on open source foundations, helping enterprises avoid vendor lock-in, benefit from the open source community, and implement it across on-premises and various cloud environments.
For this post, we use the OpenTelemetry Demo application to demonstrate our observability use case. This is an ecommerce application powered by about 20 different microservices, and generates realistic telemetry data together with feature sets to generate load and simulate failures.
Model Context Protocol servers for observability signal data
The Model Context Protocol (MCP) provides a standardized mechanism to connect agents to external data sources and tools. In this solution, we built three distinct MCP servers, one for each type of signal.
The Logs MCP server exposes tool functions for searching, filtering, and selecting log data that is stored in an OpenSearch Service domain for log data. This enables the agent to query the logs using various criteria like simple keyword matching, service name filter, log level, or time ranges. This mimics the typical queries you would run during an investigation. The following snippet shows a pseudo code of what the tool function can look like:
# Logs MCP Server - Key Functions
search_otel_logs(
    query: string,           # Text search query for log messages
    service: string,         # Service name to filter logs
    severity: string,        # Log level (INFO, WARN, ERROR)
    startTime: string,       # Start time (ISO format or relative e.g., 'now-1h')
    endTime: string,         # End time (ISO format or relative e.g., 'now')
    size: number             # Number of results to return
)
get_logs_by_trace_id(
    traceId: string,         # Trace ID to retrieve all correlated logs
    size: number             # Maximum number of logs to return
)
The Traces MCP server exposes tool functions for searching and retrieving information about distributed traces. These functions can help look up traces by trace ID and find traces for a particular service, the spans belonging to a trace, the service map information constructed based on the spans, and the rate, error, and duration (also known as RED metrics). This enables the agent to follow a request’s path across the services and pinpoint where failures happened or latency originated.
# Traces MCP Server - Key Functions
get_otel_spans(
    serviceName: string,     # Service name to filter spans
    traceId: string,         # Trace ID to filter spans
    spanId: string,          # Span ID to retrieve a specific span
    operationName: string,   # Operation/span name to filter
    startTime: string,       # Start time (ISO format or relative)
    endTime: string,         # End time (ISO format or relative)
    size: number             # Number of results to return
)
get_spans_by_trace_id(
    traceId: string,         # Trace ID to retrieve all spans for
    size: number             # Maximum number of spans to return
)
get_otel_service_map(
    serviceName: string,     # Service name to filter service map
    startTime: string,       # Start time
    endTime: string,         # End time
    size: number             # Number of results to return
)
get_otel_rate_error_duration_metrics(
    startTime: string,       # Start time (default: 'now-5m')
    endTime: string          # End time (default: 'now')
)
The Metrics MCP server exposes tool functions for querying time series metrics. The agent can use these functions to check error rate percentiles and resource utilization, which are key signals for understanding the overall health of the system and identifying anomalous behavior.
These three MCP servers span across the different types of data used by investigation engineers, providing a complete working set for an agent to conduct investigations with autonomous correlation across logs, traces, and metrics to determine the possible root causes for an issue. Additionally, a custom MCP server exposes tool functions over business data on revenue, sales, and other business metrics. For the OpenTelemetry demo application, you can develop synthetic data to aid in providing context for impact and other business level metrics. For brevity, we don’t show that server as a part of this architecture.
Observability agent
The observability agent is central to the solution. It is built to help with incident investigation. Traditional automations and manual runbooks typically follow predefined operating procedures, but with an observability agent, you don’t need to define them. The agent can analyze, reason based on the data available to it, and adapt its strategy based on what it discovers. It correlates findings across logs, traces, and metrics to arrive at a root cause.
The observability agent is built with the Strands Agent SDK, an open source framework that simplifies development of AI agents. The SDK provides a model-driven approach with flexibility to handle underlying orchestration and reasoning (the agent loop) by invoking exposed tools and maintaining coherent, turn-based interactions. This implementation also discovers tools dynamically, so if there is a change in the capabilities, the agent can make decisions based on up-to-date information.
The agent runs on Amazon Bedrock AgentCore Runtime, which provides fully managed infrastructure for hosting and running agents. The runtime supports popular agent frameworks, including Stands, LangGraph, and CrewAI. The runtime also provides scaling availability and compute that many enterprises require to run production-grade agents.
We use Amazon Bedrock AgentCore Gateway to connect to all three MCP servers. When deploying agents at scale, gateways are indispensable components to reduce management tasks like custom code development, infrastructure provisioning, comprehensive ingress and egress security, and unified access. These are essential enterprise functions needed when bringing a workload to production. In this application, we create gateways that connect all three MCP servers as targets using server-sent events. Gateways work alongside Amazon Bedrock AgentCore Identities to provide secure credentials management and secure identity propagation from the user to the communicating entities. The sample application uses AWS Identity and Access Management (IAM) for identity management and propagation.
Incident investigation is often a multi-step process. It involves iterative hypothesis testing, multiple rounds of querying, and building context over time. We use Amazon Bedrock AgentCore Memory for this purpose. In this solution, we use session-based namespaces to maintain separate conversation threads for different investigations. For example, when a user asks “What about Payment service?” during an investigation, the agent retrieves recent conversation history from memory to maintain awareness of prior findings. We store both user questions and agent responses with timestamps to help the agent reconstruct the conversation chronologically and reason about already completed findings.
We configured the observability agent to use Anthropic’s Claude Sonnet v4.5 in Amazon Bedrock for reasoning. The model interprets questions, decides which MCP tool to invoke, analyzes the results, and formulates the set of questions or conclusions. We use a system prompt to instruct the model to think like an experienced SRE or an operation center engineer: “Starting with a high-level check, narrowing down affected components, correlate across telemetry signal types and derive conclusion with substantiation. You ask the model to also suggest logical next steps such as performing a drill down to investigate inter service dependencies.” This makes the agent versatile to analyze and reason about common varieties of incident investigations.
Observability agent in action
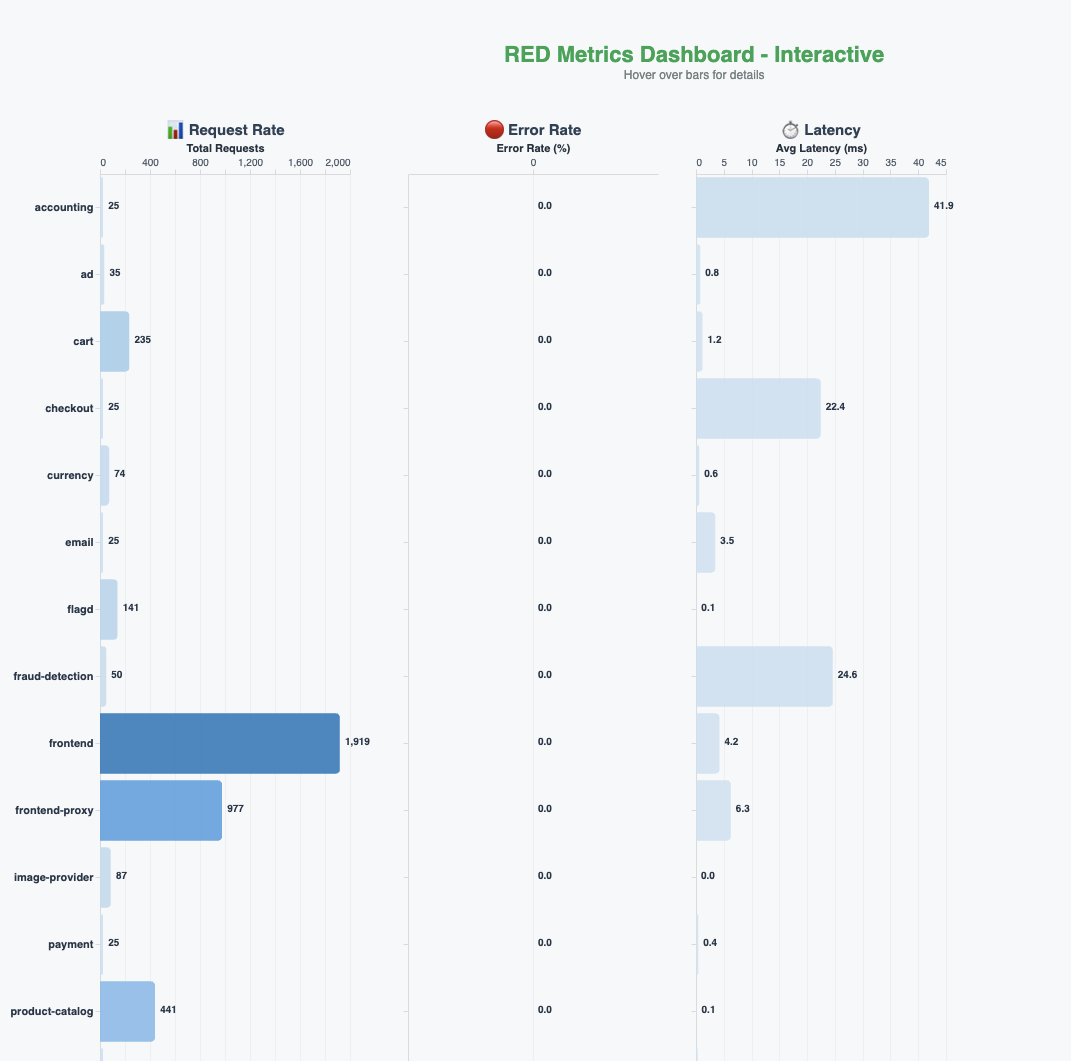
We built a real-time RED (rate, errors, duration) metrics dashboards for the entire application, as shown in the following figure.
To establish a baseline, we asked the agent the following question: “Are there any errors in my application in the last five minutes?”The agent queries the traces and metrics, analyzes the results, and responds saying there are no errors in the system. It notes that all the services are active, traces are healthy, and the system is processing requests normally. The agent also proactively suggests next steps that might be useful for further investigation.
Introducing failures
The OpenTelemetry demo application has a feature flag that we can use to introduce deliberate failures in the system. It also includes load generation so these errors can surface prominently. We use these features to introduce a few failures with the payment service. The real-time RED metrics dashboards in the previous figure reflect the impact and show the error rates climbing.
Investigation and root cause analysis
Now that we are generating errors, we engage the agent again. This is typically the start of the investigation session. Also, we have workflows like alarms triggering or pages going out that will trigger the starting of an investigation.
We ask the question “Users are complaining that it is taking a long time to buy items. Can you check to see what is going on?”
The agent retrieves the conversation history from memory (if there is any), invokes tools to query RED metrics across services, and analyzes the results. It identifies a critical purchase flow performance issue: payment service is in a connectivity crisis and completely unavailable, with extreme latency observed in fraud detection, ad service, and recommendation service. The agent provides immediate action recommendations—restore payment service connectivity as the top priority—and suggests next steps, including investigating payment service logs.
Following the agent’s suggestion, we ask it to investigate the logs: “Investigate payment service logs to understand the connectivity issue.”
The agent searches logs for the checkout and payment services, correlates them with trace data, and analyzes service dependencies from the service map. It confirms that although cart service, product catalog service, and currency service are healthy, the payment service is completely unreachable, successfully identifying the root cause of our deliberately introduced failure.
Beyond root cause: Analyzing business impact
As mentioned earlier, we have synthetic business sales and revenue data in a separate MCP server, so when the user asks the agent “Analyze the business impact of the checkout and payment service failures,” the agent uses this business data, examines the transaction data from traces, calculates estimated revenue impact, and assesses customer abandonment rates due to checkout failures. This shows how the agent can go beyond identifying the root cause and provide help with operational activities like creating a runbook for issue resolution in the future, which can be first the step to providing automatic remediation without involving SREs.
Benefits and results
Although the failure scenario in this post is simplified for illustration, it highlights several key benefits that directly contribute to reducing MTTR.
Accelerated investigation cycles
Traditional workflows for troubleshooting involve multiple iterations of hypotheses, verification, querying, and data analysis at each step, requiring context switching and consuming hours of effort. The observability agent reduces these drastically to a few minutes by autonomous reasoning, correlation, and actioning, which in turn reduces MTTR.
Handling complex workflows
Real-world production scenarios often involve cascading failures and multiple system failures. The observability agent’s capabilities can extend to these scenarios by using historical data and pattern recognition. For instance, it can distinguish related issues from false positives using temporal or identity-based correlation, dependency graphs, and other techniques, helping SREs avoid wasted investigation effort on unrelated anomalies.
Rather than provide a single answer, the agent can provide probabilistic distribution across potential root causes, helping SREs prioritize remediation methods; for example:
Payment service network connectivity issue: 75%
Downstream payment gateway timeout: 15%
Database connection pool exhaustion: 8%
Other/Unknown: 2%
The agent can compare current symptoms against past incidents, identifying whether similar patterns have happened in the past, thereby evolving from a reactive query tool into a proactive diagnostic assistant.
Conclusion
Incident investigation remains largely manual. SREs juggle dashboards, craft queries, and correlate signals under pressure, even when all the data is readily available. In this post, we showed how an observability agent built with Amazon Bedrock AgentCore and OpenSearch Service can alleviate this cognitive burden by autonomously querying logs, traces, and metrics; correlating findings; and guiding SREs toward root cause faster. Although this pattern represents one approach, the flexibility of Amazon Bedrock AgentCore combined with the search and analytics capabilities of OpenSearch Service enables agents to be designed and deployed in numerous ways—at different stages of the incident lifecycle, with varying levels of autonomy, or focused on specific investigation tasks—to suit your organization’s unique operational needs. Agentic AI doesn’t replace existing observability investment, but amplifies them by providing an effective way to use your data during incident investigations.
About the authors
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.