Tag Archives: Amazon EC2

Building a high-performance Windows workstation on AWS for graphics intensive applications

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/building-a-high-performance-windows-workstation-on-aws-for-graphics-intensive-applications/

This blog post is written by Mike Lim, Senior Public Sector SA.

Video editing, professional visualization, and video games can be resource demanding applications that require high performance Windows workstations with GPUs. When developing these resource demanding applications, a high-performance remote display protocol is desirable in order to access the instances’ graphical desktops from the internet. Using NICE DCV provides a bandwidth-adaptive streaming protocol that provides near real-time responsiveness without compromising image quality. Customers using NICE DCV can leverage Amazon EC2 G4 and Amazon EC2 G5 GPU instances which support graphic-intensive applications in the cloud using a pay-as-you-go pricing model. By using Amazon Elastic Compute Cloud (Amazon EC2) with NICE DCV, customers can run graphically intensive applications remotely and stream their user interface to simpler client machines, eliminating the need for expensive dedicated workstations.

This post shows how you can provision and manage an Amazon EC2 GPU Windows instance and access it via the high-performance NICE DCV remote display protocol.

Solution overview

The solution is illustrated in the following figure.

Solution overview

Figure 1: Solution overview

We used the AWS CloudFormation Infrastructure-as-Code (IaC) service to provision our solution. Our CloudFormation template provides the following functionality:

1.       Using AWS CloudFormation, you can specify your choice of EC2 instance type, the Amazon Virtual Private Cloud (Amazon VPC), and subnet in which to provision. You also have the option to assign a static IPv4 address. NICE DCV server is installed to provide remote access, and you can specify the choice of graphics driver to install.

2.       A security group is created and associated with the EC2 instance, and it acts as a firewall.

3.       An AWS Identity and Access Management (IAM) role is created and associated with the EC2 instance using an instance profile. It lets your instance access Amazon Simple Storage Service (Amazon S3) buckets for NICE DCV server license validation, and download and install the latest graphics drivers.

4.       The IAM role also makes sure that your EC2 instance can be managed by AWS Systems Manager. This service provides in-browser command line and graphical access to your Windows instance via Session Manager and Fleet Manager from the AWS Management Console.

Walkthrough

The following sections walk through the steps to setup and maintain your graphics workstation. To begin, you need an AWS account. For this walkthrough, we provision a g5.xlarge instance for cloud gaming.

Check instance type availability

For best performance and lowest latency, you will want to provision EC2 in the AWS Region nearest to you. Before proceeding, verify that the g5.xlarge instance type is available in your desired AWS Region, and the Availability Zones (AZs) in which it is available.

Log in to your Amazon EC2 console and select your AWS Region. From the navigation pane, choose Instance Types to view the instance types available. In the search bar, filter instances types to the specific instance type you want, in this case g5.xlarge. Toggle the display preferences (gear) icon to display Availability zones column.

In the following screenshot, the g5.xlarge instance is available in two of the three AZs in eu-west-2 Europe London Region.

Amazon EC2 console instance types

Figure 2: Amazon EC2 console instance types

Check Amazon EC2 running on-demand G instances quota

Your AWS account has a limit on the number and type of EC2 instances types you can run, and you need to make sure you have enough quota to run the g5.xlarge instance.

Go to the Service Quotas console for your AWS Region. Under AWS services in the navigation pane, select Amazon Elastic Compute Cloud (Amazon EC2) and search for Running On-Demand G and VT instances. Verify that the Applied quota value number is equal or more than the number of vCPUs for the instance size you need. In the following screenshot, the applied quota value is 64. It lets us launch instance sizes from 4 vCPUs xlarge up to 64 vCPUs 16xlarge instance size.

Service Quotas console

Figure 3: Service Quotas console

You can request a higher quota value by selecting Request quota increase.

Using CloudFormation template

Download the CloudFormation template file from aws-samples GitHub repository. Go to the CloudFormation console for your AWS Region to create a stack, and upload your downloaded file.

The CloudFormation parameters page is divided into the following sections:

  1. AMI and instance type
  2. EC2 configuration
  3. Allowed inbound source IP prefixes to NICE DCV port 8443
  4. EBS volume configuration

We go through the configuration settings for each section in detail.

AMI and instance type

In this section, we select the Windows Amazon Machine Image (AMI) to use, EC2 instance type to provision, and graphics driver to install. The default AMI is Microsoft Windows Server 2022.

Replace the instanceType value with g5.xlarge.

CloudFormation parameters: AMI and instance type

Figure 4: CloudFormation parameters: AMI and instance type

Select driverType based on your instance type and the following use case:

  1. AMD: select this for instance types with AMD GPU (G4ad instance).
  2. NVIDIA-Gaming: select this to install the NVIDIA gaming driver, which is optimized for gaming (G5 and G4dn instances).
  3. NVIDIA-GRID: select this to install the GRID driver, which is optimized for professional visualization applications that render content such as 3D models or high-resolution videos (G5, G4dn, and G3 instances).
  4. none: select this option for accelerated computing instances, such as P2 and P3 instances where you download and install public NVIDIA drivers manually.
  5. NICE-DCV: this installs the NICE DCV Virtual Display driver and is suitable for all other instance types.

Note that GRID and NVIDIA gaming drivers’ downloads are available to AWS customers only. Upon installation of the software, you are bound by the terms of the NVIDIA GRID Cloud End User License Agreement.

For our walkthrough, select NVIDIA-Gaming for driverType.

Amazon EC2 configuration

In this section, we specify the VPC and subnet in which to provision our EC2 instance. You can select default VPC from the vpcID dropdown. Make sure that the subnetID value you select is in your selected VPC and resides in an AZ that has your instance type offering. You can also change the EC2 instance name.

Select Yes for the assignStaticIP option if you want to associate a static Internet IPv4 address. Note that there is a small hourly charge when the instance is not running.

CloudFormation parameters: Amazon EC2 configuration

Figure 5: CloudFormation parameters: Amazon EC2 configuration

Allowed inbound source IP prefixes to NICE DCV port 8443

Here, we specify the source prefixes allowed to access our instance. The default values allow access from all addresses. To secure access to your instance, you may want to limit the source prefix to your IP address.

To get your IPv4 address, go to https://checkip.amazonaws.com and append /32 to the value for ingressIPv4. The default VPC and subnet is IPv4 only. Therefore, you can enter ::1/128 to explicitly block all IPv6 access for ingressIPv6.

CloudFormation parameters: Allowed inbound source IP prefixes

Figure 6: CloudFormation parameters: Allowed inbound source IP prefixes

Amazon EBS volume configuration

The default Amazon Elastic Block Store (Amazon EBS) volume size is 30 GiB. You can specify a larger size by changing the volumeSize value.

CloudFormation parameters: Amazon EBS volume configuration

Figure 7: CloudFormation parameters: Amazon EBS volume configuration

Continue to provision your stack.

NICE DCV client

NICE DCV provides an HTML5 client for web browser access. For performance and additional features, such as QUIC UDP transport protocol support and USB remotization support, install the native client from the NICE DCV download page. NICE DCV offers native clients for Windows, MacOS for both Intel and Apple M1 processors, and modern Linux distributions including RHEL, SUSE Linux, and Ubuntu.

Cloudformation Outputs

Once provisioning is complete, go to the Outputs section.

CloudFormation Outputs

Figure 8: CloudFormation Outputs

The following URLs are available.

  1. DCVwebConsole
  2. EC2instance
  3. RdpConnect
  4. SSMsessionManager

We go through the purpose of each URL in the following sections.

SSMsessionManager: Change administrator password

To log in, you must specify an administrator password. Open the SSMsessionManager value URL in a new browser tab and run the command net user administrator <YOUR-PASSWORD> where <YOUR-PASSWORD> is the password on which you decided.

Systems Manager session manager

Figure 9: Systems Manager session manager

DCVwebConsole: Connecting to the EC2 instance

Copy DCVWebConsole value, open the NICE DCV client from your local machine and either use the copied value or the IP address to connect. Log in as administrator with the password that you have configured. Alternatively, enter the URL in the format dcv://<EC2-IP-Address> in a browser URL bar to automatically launch and connect a locally installed NICE DCV client to your EC2 instance.

NICE DCV client

Figure 10: NICE DCV client

EC2instance: manage EC2 instance

Use this link to manage your EC2 instance in the Amazon EC2 console. If you did not select the static IP address option, then use this page to get the assigned IP address whenever you stop and start your instance.

RdpConnect: Fleet Manager console access

The RdpConnect link provides in-browser Remote Desktop Protocol (RDP) console access to your Windows instance. Choose User credentials for Authentication Type. Enter administrator for username and the password that you have configured.

Fleet Manager Remote Desktop

Figure 11: Fleet Manager Remote Desktop

Updating NICE DCV server

To update NICE DCV server, log in via Fleet Manager Remote Desktop and run c:\users\administrator\update-DCV.cmd script. In the following screenshot, we successfully upgraded NICE DCV server from version 2022.2-14521 to 2023.0-15065.

Updating NICE DCV server

Figure 12: Updating NICE DCV server

Updating graphics drivers

You can use the download-<DRIVER_TYPE>-driver.cmd batch file to download the latest graphics driver for your instance type GPU. Downloaded files are located in the Downloads\Drivers folder.

Graphics driver download scripts

Figure 13: Graphics driver download scripts

AWS Command Line interface (AWS CLI v2) is installed in the instance. You can use it to view the different versions available on the driver S3 bucket. For example, the command aws s3 ls –recursive s3://nvidia-gaming/windows/ | sort /R lists NVIDIA gaming drivers available for download. NVIDIA GRID and AMD drivers are in the s3://ec2-windows-nvidia-drivers and s3://ec2-amd-windows-drivers S3 buckets respectively.

Listing graphics drivers on S3 bucket

Figure 14: Listing graphics drivers on S3 bucket

Use the command aws s3 cp s3://<S3_BUCKET_PATH>/<FILE-NAME>. to copy a specific driver from the S3 bucket to your local directory.

You can refer to Install NVIDIA drivers on Windows instances and Install AMD drivers on Windows instances for NVIDIA and AMD drivers installation instructions respectively.

Customizing your EC2 instance environment

You may want to customize the instance to your needs. For NVIDIA GPU instances, you can optimize GPU settings to achieve the best performance.

If you are doing video editing, then you can enable high color accuracy, configure multi-channel audio, and enable accurate audio/video sync. For gaming, you may enable gamepad support to use a DualShock 4 or Xbox 360 controller. NICE DCV session storage is enabled. This lets you transfer files using NICE DCV client. More configuration options are available from the NICE DCV User Guide and Administrator Guide.

Terminating your EC2 instance

When you have finished using your EC2 instance, you can release all provisioned resources by going to CloudFormation console to delete your stack.

Conclusion

The Amazon G4 and G5 GPU instance types are suitable for graphics-intensive applications, and NICE DCV provides a responsive and high image quality display protocol for remote access. Using the CloudFormation template from amazon-ec2-nice-dcv-samples GitHub site, you can build and maintain your own high performance Windows graphics workstation in the AWS cloud

AWS Cloud service considerations for designing multi-tenant SaaS solutions

Post Syndicated from Dennis Greene original https://aws.amazon.com/blogs/architecture/aws-cloud-service-considerations-for-designing-multi-tenant-saas-solutions/

An increasing number of software as a service (SaaS) providers are considering the move from single to multi-tenant to utilize resources more efficiently and reduce operational costs. This blog aims to inform customers of considerations when evaluating a transformation to multi-tenancy in the Amazon Web Services (AWS) Cloud. You’ll find valuable information on how to optimize your cloud-based SaaS design to reduce operating expenses, increase resiliency, and offer a high-performing experience for your customers.

Single versus multi-tenancy

In a multi-tenant architecture, resources like compute, storage, and databases can be shared among independent tenants. In contrast, a single-tenant architecture allocates exclusive resources to each tenant.

Let’s consider a SaaS product that needs to support many customers, each with their own independent deployed website. Using a single-tenant model (see Figure 1), the SaaS provider may opt to utilize a dedicated AWS account to host each tenant’s workloads. To contain their respective workloads, each tenant would have their own Amazon Elastic Compute Cloud (Amazon EC2) instances organized within an Auto Scaling group. Access to the applications running in these EC2 instances would be done via an Application Load Balancer (ALB). Each tenant would be allocated their own database environment using Amazon Relational Database Service (RDS). The website’s storage (consisting of PHP, JavaScript, CSS, and HTML files) would be provided by Amazon Elastic Block Store (EBS) volumes attached to the EC2 instances. The SaaS provider would have a control plane AWS account used to create and modify these tenant-specific accounts.

Single-tenant configuration

Figure 1. Single-tenant configuration

To transition to a multi-tenant pattern, the SaaS provider can use containerization to package each website, and a container orchestrator to deploy the websites across shared compute nodes (EC2 instances). Kubernetes can be employed as a container orchestrator, and a website would then be represented by a Kubernetes deployment and its associated pods. A Kubernetes namespace would serve as the logical encapsulation of the tenant-specific resources, as each tenant would be mapped to one Kubernetes namespace. The Kubernetes HorizontalPodAutoscaler can be utilized for autoscaling purposes, dynamically adjusting the number of replicas in the deployment on a given namespace based on workload demands.

When additional compute resources are required, tools such as the Cluster Autoscaler, or Karpenter, can dynamically add more EC2 instances to the shared Kubernetes Cluster. An ALB can be reused by multiple tenants to route traffic to the appropriate pods. For RDS, SaaS providers can use tenant-specific database schemas to separate tenant data. For static data, Amazon Elastic File System (EFS) and tenant-specific directories can be employed. The SaaS provider would still have a control plane AWS account that would now interact with the Kubernetes and AWS APIs to create and update tenant-specific resources.

This transition to a multi-tenant design utilizing Kubernetes, Amazon Elastic Kubernetes Service (EKS), and other managed services offers numerous advantages. It enables efficient resource utilization by leveraging containerization and auto-scaling capabilities, reducing costs, and optimizing performance (see Figure 2).

Multi-tenant configuration

Figure 2. Multi-tenant configuration

EKS cluster sizing and customer segmentation considerations in multi-tenancy designs

A high concentration of SaaS tenants hosted within the same system results in a large “blast radius.” This means a failure within the system has the potential to impact all resident tenants. This situation can lead to downtime for multiple tenants at once. To address this problem, SaaS providers are encouraged to partition their customers amongst multiple AWS accounts, each with their own deployments of this multi-tenant architecture. The number of tenants that can be present in a single cluster is a determination that can only be made by the SaaS provider after weighing the risks. Compare the shared fate of some subset of their customers, against the possible efficiency benefits of a multi-tenant architecture.

EKS security

SaaS providers must evaluate whether it’s appropriate for them to make use of containers as a workload isolation boundary. This is of particular importance in multi-tenant Kubernetes architectures, given that containers running on a single Amazon EC2 instance will share the underlying Linux kernel. Security vulnerabilities place this shared resource (the EC2 instance) at risk from attack vectors from the host Linux instance. Risk is elevated when any container running in a Kubernetes Pod cluster initiates untrusted code. This risk is heightened if SaaS providers permit tenants to “bring their code”. Kubernetes is a single tenant orchestrator, but with a multi-tenant approach to SaaS architectures, a single instance of the Amazon EKS control plane will be shared among all the workloads running within a cluster. Amazon EKS considers the cluster as the hard isolation security boundary. Every Amazon EKS managed Kubernetes cluster is isolated in a dedicated single-tenant Amazon VPC. At present, hard multi-tenancy can only be implemented by provisioning a unique cluster for each tenant.

EFS considerations

A SaaS provider may consider EFS as the storage solution for the static content of the multiple tenants. This provides them with a straightforward, serverless, and elastic file system. Directories may be used to separate the content for each tenant. While this approach of creating tenant-specific directories in EFS provides many benefits, there may be challenges harvesting per-tenant utilization and performance metrics. This can result in operational challenges for providers that need to granularly meter per-tenant usage of resources. Consequently, noisy neighbors will be difficult to identify and remediate. To resolve this, SaaS providers should consider building a custom solution to monitor the individual tenants in the multi-tenant file system by leveraging storage and throughput/IOPS metrics.

RDS considerations

Multi-tenant workloads, where data for multiple customers or end users is consolidated in the same RDS database cluster, can present operational challenges regarding per-tenant observability. Both MySQL Community Edition and open-source PostgreSQL have limited ability to provide per-tenant observability and resource governance. AWS customers operating multi-tenant workloads often use a combination of ‘database’ or ‘schema’ and ‘database user’ accounts as substitutes. AWS customers should use alternate mechanisms to establish a mapping between a tenant and these substitutes. This will give you the ability to process raw observability data from the database engine externally. You can then map these substitutes back to tenants, and distinguish tenants in the observability data.

Conclusion

In this blog, we’ve shown what to consider when moving to a multi-tenancy SaaS solution in the AWS Cloud, how to optimize your cloud-based SaaS design, and some challenges and remediations. Invest effort early in your SaaS design strategy to explore your customer requirements for tenancy. Work backwards from your SaaS tenants end goals. What level of computing performance do they require? What are the required cyber security features? How will you, as the SaaS provider, monitor and operate your platform with the target tenancy configuration? Your respective AWS account team is highly qualified to advise on these design decisions. Take advantage of reviewing and improving your design using the AWS Well-Architected Framework. The tenancy design process should be followed by extensive prototyping to validate functionality before production rollout.

Related information

New Seventh-Generation General Purpose Amazon EC2 Instances (M7i-Flex and M7i)

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-seventh-generation-general-purpose-amazon-ec2-instances-m7i-flex-and-m7i/

Today we are launching Amazon Elastic Compute Cloud (Amazon EC2) M7i-Flex and M7i instances powered by custom 4th generation Intel Xeon Scalable processors available only on AWS, that offer the best performance among comparable Intel processors in the cloud – up to 15% faster than Intel processors utilized by other cloud providers. M7i-Flex instances are available in the five most common sizes, and are designed to give you up to 19% better price/performance than M6i instances for many workloads. The M7i instances are available in nine sizes (with two size of bare metal instances in the works), and offer 15% better price/performance than the previous generation of Intel-powered instances.

M7i-Flex Instances
The M7i-Flex instances are a lower-cost variant of the M7i instances, with 5% better price/performance and 5% lower prices. They are great for applications that don’t fully utilize all compute resources. The M7i-Flex instances deliver a baseline of 40% CPU performance, and can scale up to full CPU performance 95% of the time. M7i-Flex instances are ideal for running general purpose workloads such as web and application servers, virtual desktops, batch processing, micro-services, databases and enterprise applications. If you are currently using earlier generations of general-purposes instances, you can adopt M7i-Flex instances without having to make changes to your application or your workload.

Here are the specs for the M7i-Flex instances:

Instance Name vCPUs
Memory
Network Bandwidth
EBS Bandwidth
m7i-flex.large 2 8 GiB up to 12.5 Gbps up to 10 Gbps
m7i-flex.xlarge 4 16 GiB up to 12.5 Gbps up to 10 Gbps
m7i-flex.2xlarge 8 32 GiB up to 12.5 Gbps up to 10 Gbps
m7i-flex.4xlarge 16 64 GiB up to 12.5 Gbps up to 10 Gbps
m7i-flex.8xlarge 32 128 GiB up to 12.5 Gbps up to 10 Gbps

M7i Instances
For workloads such as large application servers and databases, gaming servers, CPU based machine learning, and video streaming that need the largest instance sizes or high CPU continuously, you can get price/performance benefits by using M7i instances.

Here are the specs for the M7i instances:

Instance Name vCPUs
Memory
Network Bandwidth
EBS Bandwidth
m7i.large 2 8 GiB up to 12.5 Gbps up to 10 Gbps
m7i.xlarge 4 16 GiB up to 12.5 Gbps up to 10 Gbps
m7i.2xlarge 8 32 GiB up to 12.5 Gbps up to 10 Gbps
m7i.4xlarge 16 64 GiB up to 12.5 Gbps up to 10 Gbps
m7i.8xlarge 32 128 GiB 12.5 Gbps 10 Gbps
m7i.12xlarge 48 192 GiB 18.75 Gbps 15 Gbps
m7i.16xlarge 64 256 GiB 25.0 Gbps 20 Gbps
m7i.24xlarge 96 384 GiB 37.5 Gbps 30 Gbps
m7i.48xlarge 192 768 GiB 50 Gbps 40 Gbps

You can attach up to 128 EBS volumes to each M7i instance; by way of comparison, the M6i instances allow you to attach up to 28 volumes.

We are also getting ready to launch two sizes of bare metal M7i instances:

Instance Name vCPUs
Memory
Network Bandwidth
EBS Bandwidth
m7i.metal-24xl 96 384 GiB 37.5 Gbps 30 Gbps
m7i.metal-48xl 192 768 GiB 50.0 Gbps 40 Gbps

Built-In Accelerators
The Sapphire Rapids processors include four built-in accelerators, each providing hardware acceleration for a specific workload:

  • Advanced Matrix Extensions (AMX) – This set of extensions to the x86 instruction set improve deep learning and inferencing, and support workloads such as natural language processing, recommendation systems, and image recognition. The extensions provide high-speed multiplication operations on 2-dimensional matrices of INT8 or BF16 values. To learn more, read Chapter 3 of the Intel AMX Instruction Set Reference.
  • Intel Data Streaming Accelerator (DSA) – This accelerator drives high performance for storage, networking, and data-intensive workloads by offloading common data movement tasks between CPU, memory, caches, network devices, and storage devices, improving streaming data movement and transformation operations. Read Introducing the Intel Data Streaming Accelerator (Intel DSA) to learn more.
  • Intel In-Memory Analytics Accelerator (IAA) – This accelerator runs database and analytic workloads faster, with the potential for greater power efficiency. In-memory compression, decompression, and encryption at very high throughput, and a suite of analytics primitives support in-memory databases, open source database, and data stores like RocksDB and ClickHouse. To learn more, read the Intel In-Memory Analytics Accelerator (Intel IAA) Architecture Specification.
  • Intel QuickAssist Technology (QAT) -This accelerator offloads encryption, decryption, and compression, freeing up processor cores and reducing power consumption. It also supports merged compression and encryption in a single data flow. To learn more start at the Intel QuickAssist Technology (Intel QAT) Overview.

Some of these accelerators require the use of specific kernel versions, drivers, and/or compilers.

The Advanced Matrix Extensions are available on all sizes of M7i and M7i-Flex instances. The Intel QAT, Intel IAA, and Intel DSA accelerators will be available on the m7i.metal-24xl and m7i.metal-48xl instances.

Details
Here are a couple of things to keep in mind about the M7i-Flex and M7i instances:

Regions – The new instances are available in the US East (Ohio, N. Virginia), US West (Oregon), and Europe (Ireland) AWS Regions, and we plan to expand to additional regions throughout the rest of 2023.

Purchasing Options – M7i-Flex amd M7i instances are available in On-Demand, Reserved Instance, Savings Plan, and Spot form. M7i instances are also available in Dedicated Host and Dedicated Instance form.

— Jeff;

Prime Day 2023 Powered by AWS – All the Numbers

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/prime-day-2023-powered-by-aws-all-the-numbers/

As part of my annual tradition to tell you about how AWS makes Prime Day possible, I am happy to be able to share some chart-topping metrics (check out my 2016, 2017, 2019, 2020, 2021, and 2022 posts for a look back).

This year I bought all kinds of stuff for my hobbies including a small drill press, filament for my 3D printer, and irrigation tools. I also bought some very nice Alphablock books for my grandkids. According to our official release, the first day of Prime Day was the single largest sales day ever on Amazon and for independent sellers, with more than 375 million items purchased.

Prime Day by the Numbers
As always, Prime Day was powered by AWS. Here are some of the most interesting and/or mind-blowing metrics:

Amazon Elastic Block Store (Amazon EBS) – The Amazon Prime Day event resulted in an incremental 163 petabytes of EBS storage capacity allocated – generating a peak of 15.35 trillion requests and 764 petabytes of data transfer per day. Compared to the previous year, Amazon increased the peak usage on EBS by only 7% Year-over-Year yet delivered +35% more traffic per day due to efficiency efforts including workload optimization using Amazon Elastic Compute Cloud (Amazon EC2) AWS Graviton-based instances. Here’s a visual comparison:

AWS CloudTrail – AWS CloudTrail processed over 830 billion events in support of Prime Day 2023.

Amazon DynamoDB – DynamoDB powers multiple high-traffic Amazon properties and systems including Alexa, the Amazon.com sites, and all Amazon fulfillment centers. Over the course of Prime Day, these sources made trillions of calls to the DynamoDB API. DynamoDB maintained high availability while delivering single-digit millisecond responses and peaking at 126 million requests per second.

Amazon Aurora – On Prime Day, 5,835 database instances running the PostgreSQL-compatible and MySQL-compatible editions of Amazon Aurora processed 318 billion transactions, stored 2,140 terabytes of data, and transferred 836 terabytes of data.

Amazon Simple Email Service (SES) – Amazon SES sent 56% more emails for Amazon.com during Prime Day 2023 vs. 2022, delivering 99.8% of those emails to customers.

Amazon CloudFront – Amazon CloudFront handled a peak load of over 500 million HTTP requests per minute, for a total of over 1 trillion HTTP requests during Prime Day.

Amazon SQS – During Prime Day, Amazon SQS set a new traffic record by processing 86 million messages per second at peak. This is 22% increase from Prime Day of 2022, where SQS supported 70.5M messages/sec.

Amazon Elastic Compute Cloud (EC2) – During Prime Day 2023, Amazon used tens of millions of normalized AWS Graviton-based Amazon EC2 instances, 2.7x more than in 2022, to power over 2,600 services. By using more Graviton-based instances, Amazon was able to get the compute capacity needed while using up to 60% less energy.

Amazon Pinpoint – Amazon Pinpoint sent tens of millions of SMS messages to customers during Prime Day 2023 with a delivery success rate of 98.3%.

Prepare to Scale
Every year I reiterate the same message: rigorous preparation is key to the success of Prime Day and our other large-scale events. If you are preparing for a similar chart-topping event of your own, I strongly recommend that you take advantage of AWS Infrastructure Event Management (IEM). As part of an IEM engagement, my colleagues will provide you with architectural and operational guidance that will help you to execute your event with confidence!

— Jeff;

New – AWS Public IPv4 Address Charge + Public IP Insights

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-aws-public-ipv4-address-charge-public-ip-insights/

We are introducing a new charge for public IPv4 addresses. Effective February 1, 2024 there will be a charge of $0.005 per IP per hour for all public IPv4 addresses, whether attached to a service or not (there is already a charge for public IPv4 addresses you allocate in your account but don’t attach to an EC2 instance).

Public IPv4 Charge
As you may know, IPv4 addresses are an increasingly scarce resource and the cost to acquire a single public IPv4 address has risen more than 300% over the past 5 years. This change reflects our own costs and is also intended to encourage you to be a bit more frugal with your use of public IPv4 addresses and to think about accelerating your adoption of IPv6 as a modernization and conservation measure.

This change applies to all AWS services including Amazon Elastic Compute Cloud (Amazon EC2), Amazon Relational Database Service (RDS) database instances, Amazon Elastic Kubernetes Service (EKS) nodes, and other AWS services that can have a public IPv4 address allocated and attached, in all AWS regions (commercial, AWS China, and GovCloud). Here’s a summary in tabular form:

Public IP Address Type Current Price/Hour (USD) New Price/Hour (USD)
(Effective February 1, 2024)
In-use Public IPv4 address (including Amazon provided public IPv4 and Elastic IP) assigned to resources in your VPC, Amazon Global Accelerator, and AWS Site-to-site VPN tunnel No charge $0.005
Additional (secondary) Elastic IP Address on a running EC2 instance $0.005 $0.005
Idle Elastic IP Address in account $0.005 $0.005

The AWS Free Tier for EC2 will include 750 hours of public IPv4 address usage per month for the first 12 months, effective February 1, 2024. You will not be charged for IP addresses that you own and bring to AWS using Amazon BYOIP.

Starting today, your AWS Cost and Usage Reports automatically include public IPv4 address usage. When this price change goes in to effect next year you will also be able to use AWS Cost Explorer to see and better understand your usage.

As I noted earlier in this post, I would like to encourage you to consider accelerating your adoption of IPv6. A new blog post shows you how to use Elastic Load Balancers and NAT Gateways for ingress and egress traffic, while avoiding the use of a public IPv4 address for each instance that you launch. Here are some resources to show you how you can use IPv6 with widely used services such as EC2, Amazon Virtual Private Cloud (Amazon VPC), Amazon Elastic Kubernetes Service (EKS), Elastic Load Balancing, and Amazon Relational Database Service (RDS):

Earlier this year we enhanced EC2 Instance Connect and gave it the ability to connect to your instances using private IPv4 addresses. As a result, you no longer need to use public IPv4 addresses for administrative purposes (generally using SSH or RDP).

Public IP Insights
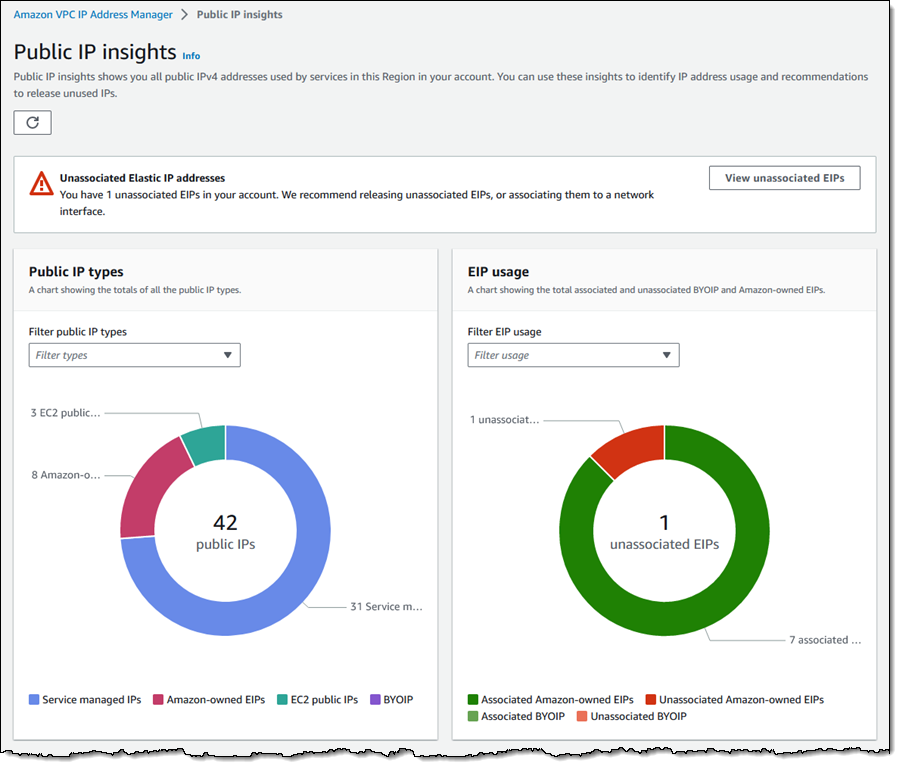
In order to make it easier for you to monitor, analyze, and audit your use of public IPv4 addresses, today we are launching Public IP Insights, a new feature of Amazon VPC IP Address Manager that is available to you at no cost. In addition to helping you to make efficient use of public IPv4 addresses, Public IP Insights will give you a better understanding of your security profile. You can see the breakdown of public IP types and EIP usage, with multiple filtering options:

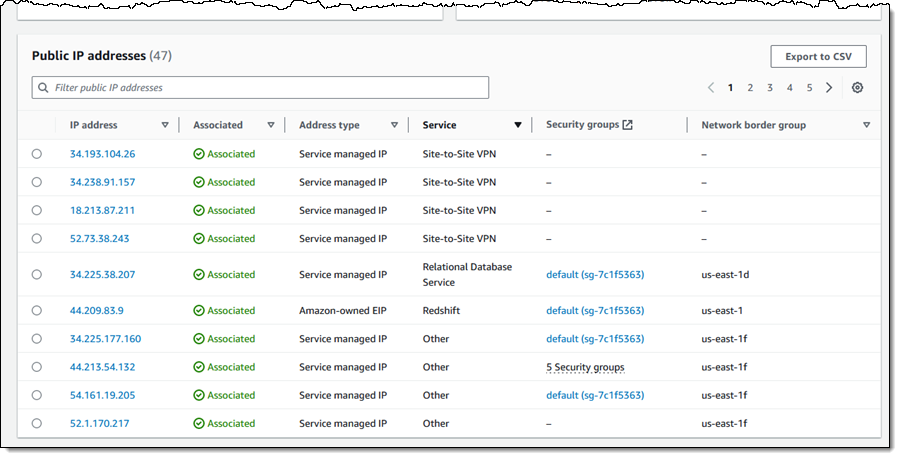
You can also see, sort, filter, and learn more about each of the public IPv4 addresses that you are using:

Using IPv4 Addresses Efficiently
By using the new IP Insights tool and following the guidance that I shared above, you should be ready to update your application to minimize the effect of the new charge. You may also want to consider using AWS Direct Connect to set up a dedicated network connection to AWS.

Finally, be sure to read our new blog post, Identify and Optimize Public IPv4 Address Usage on AWS, for more information on how to make the best use of public IPv4 addresses.

— Jeff;

New Amazon EC2 Instances (C7gd, M7gd, and R7gd) Powered by AWS Graviton3 Processor with Local NVMe-based SSD Storage

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-instances-c7gd-m7gd-and-r7gd-powered-by-aws-graviton3-processor-with-local-nvme-based-ssd-storage/

We launched Amazon EC2 C7g instances in May 2022 and M7g and R7g instances in February 2023. Powered by the latest AWS Graviton3 processors, the new instances deliver up to 25 percent higher performance, up to two times higher floating-point performance, and up to 2 times faster cryptographic workload performance compared to AWS Graviton2 processors.

Graviton3 processors deliver up to 3 times better performance compared to AWS Graviton2 processors for machine learning (ML) workloads, including support for bfloat16. They also support DDR5 memory that provides 50 percent more memory bandwidth compared to DDR4. Graviton3 also uses up to 60 percent less energy for the same performance as comparable EC2 instances, which helps you reduce your carbon footprint.

The C7g instances are well suited for compute-intensive workloads, such as high performance computing (HPC), batch processing, ad serving, video encoding, gaming, scientific modeling, distributed analytics, and CPU-based machine learning inference. The M7g instances are for general purpose workloads such as application servers, microservices, gaming servers, mid-sized data stores, and caching fleets. The R7g instances are a great fit for memory-intensive workloads such as open-source databases, in-memory caches, and real-time big data analytics.

Today, we’re adding a d variant to all three instance families. The new Amazon EC2 C7gd, M7gd, and R7gd instance types have NVM Express (NVMe) locally attached up to 2 x 1.9 TB SSD drives that are physically connected to the host server and provide block-level storage that is coupled to the lifetime of the instance. These instances have up to 45 percent better real-time NVMe storage performance than comparable Graviton2-based instances.

These are a great fit for applications that need access to high-speed, low-latency local storage, including those that need temporary storage of data for scratch space, temporary files, and caches. The data on an instance store volume persists only during the life of the associated EC2 instance.

Here are the specs for these instances:

Instance Size vCPU Memory
(GiB)
Local NVMe Storage (GB) Network Bandwidth
(Gbps)
EBS Bandwidth
(Gbps)
C7gd/M7gd/R7gd C7gd/M7gd/R7gd C7gd/M7gd/R7gd
medium 1 2/ 4 / 8 1 x 59 Up to 12.5 Up to 10
large 2 4 / 8 / 16 1 x 118 Up to 12.5 Up to 10
xlarge 4 8 / 16 / 32 1 x 237 Up to 12.5 Up to 10
2xlarge 8 16 / 32 / 64 1 x 474 Up to 15 Up to 10
4xlarge 16 32 / 64 / 128 1 x 950 Up to 15 Up to 10
8xlarge 32 64 / 128 / 256 1 x 1900 15 10
12xlarge 48 96 / 192/ 384 2 x 1425 22.5 15
16xlarge 64 128 / 256 / 512 2 x 1900 30 20

These instances are built on the AWS Nitro System, a combination of AWS-designed dedicated hardware and a lightweight hypervisor that allows the delivery of isolated multitenancy, private networking, and fast local storage. They provide up to 20 Gbps Amazon Elastic Block Store (Amazon EBS) bandwidth and up to 30 Gbps network bandwidth. The 16xlarge instances also support Elastic Fabric Adapter (EFA) for applications that need a high level of inter-node communication.

Now Available
Amazon EC2 C7gd, M7gd, and R7gd instances are now available in the following AWS Regions: US East (Ohio), US East (N. Virginia), US West (Oregon), and Europe (Ireland). As usual with Amazon EC2, you only pay for what you use. For more information, see the Amazon EC2 pricing page.

If you’re optimizing applications for Arm architecture, be sure to have a look at our Getting Started collection of resources or learn more about AWS Graviton3-based EC2 instances.

To learn more, visit our Amazon EC2 C7g instances, M7g instances or R7g instances page, and please send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

New – Amazon EC2 P5 Instances Powered by NVIDIA H100 Tensor Core GPUs for Accelerating Generative AI and HPC Applications

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-p5-instances-powered-by-nvidia-h100-tensor-core-gpus-for-accelerating-generative-ai-and-hpc-applications/

In March 2023, AWS and NVIDIA announced a multipart collaboration focused on building the most scalable, on-demand artificial intelligence (AI) infrastructure optimized for training increasingly complex large language models (LLMs) and developing generative AI applications.

We preannounced Amazon Elastic Compute Cloud (Amazon EC2) P5 instances powered by NVIDIA H100 Tensor Core GPUs and AWS’s latest networking and scalability that will deliver up to 20 exaflops of compute performance for building and training the largest machine learning (ML) models. This announcement is the product of more than a decade of collaboration between AWS and NVIDIA, delivering the visual computing, AI, and high performance computing (HPC) clusters across the Cluster GPU (cg1) instances (2010), G2 (2013), P2 (2016), P3 (2017), G3 (2017), P3dn (2018), G4 (2019), P4 (2020), G5 (2021), and P4de instances (2022).

Most notably, ML model sizes are now reaching trillions of parameters. But this complexity has increased customers’ time to train, where the latest LLMs are now trained over the course of multiple months. HPC customers also exhibit similar trends. With the fidelity of HPC customer data collection increasing and data sets reaching exabyte scale, customers are looking for ways to enable faster time to solution across increasingly complex applications.

Introducing EC2 P5 Instances
Today, we are announcing the general availability of Amazon EC2 P5 instances, the next-generation GPU instances to address those customer needs for high performance and scalability in AI/ML and HPC workloads. P5 instances are powered by the latest NVIDIA H100 Tensor Core GPUs and will provide a reduction of up to 6 times in training time (from days to hours) compared to previous generation GPU-based instances. This performance increase will enable customers to see up to 40 percent lower training costs.

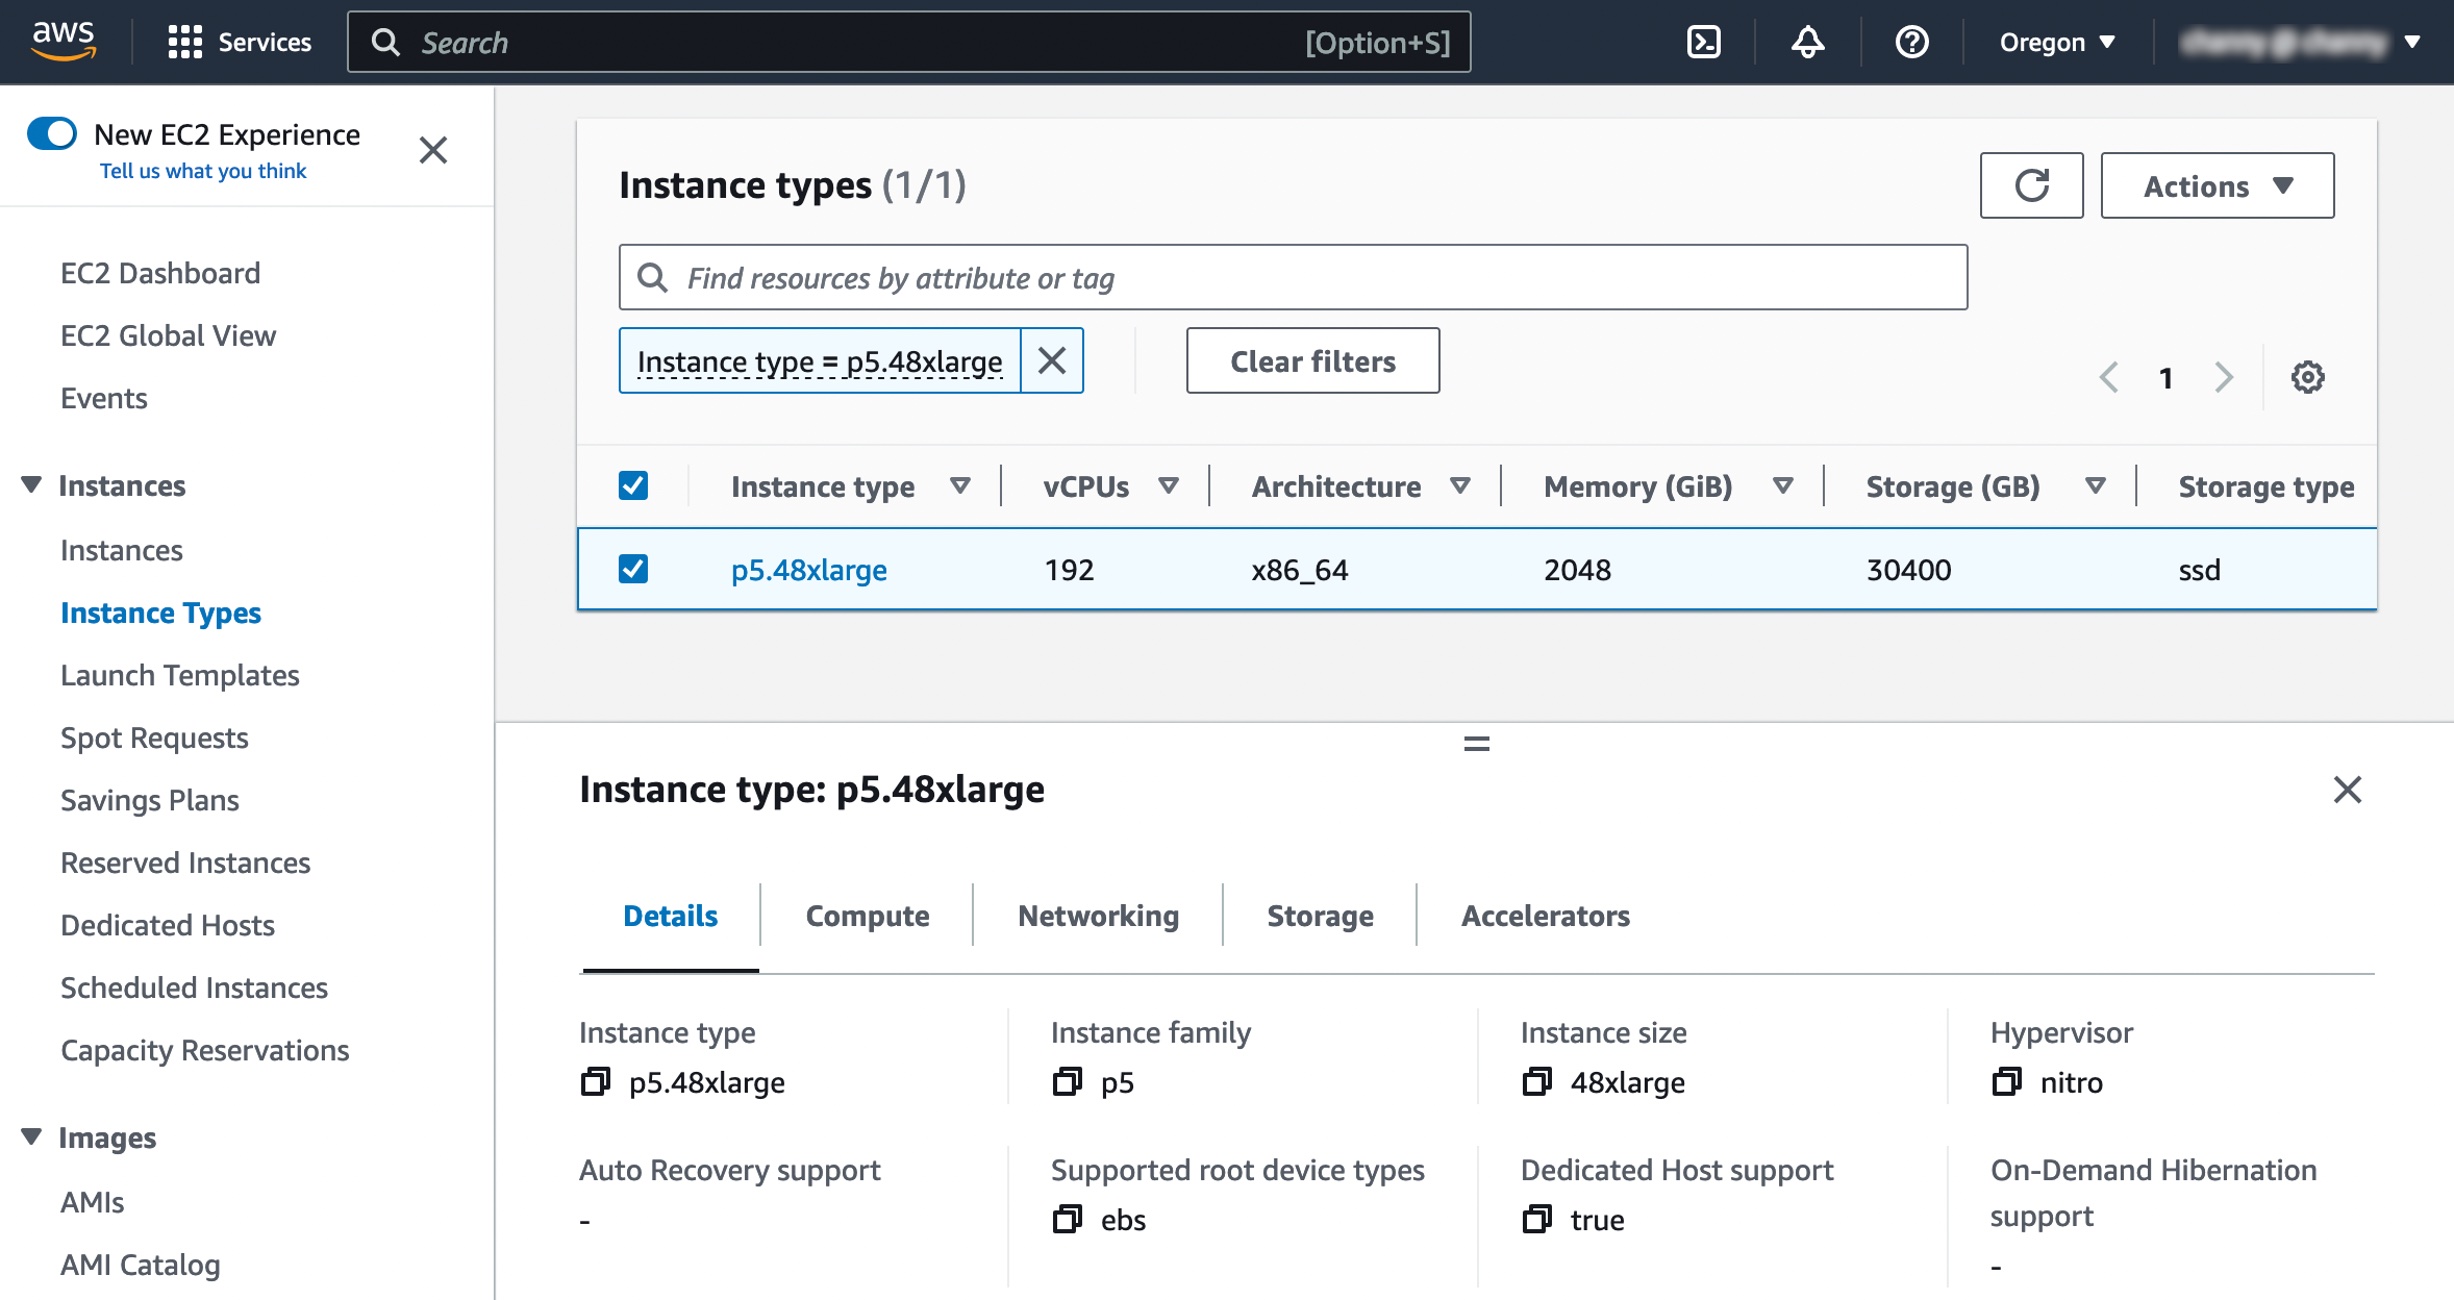
P5 instances provide 8 x NVIDIA H100 Tensor Core GPUs with 640 GB of high bandwidth GPU memory, 3rd Gen AMD EPYC processors, 2 TB of system memory, and 30 TB of local NVMe storage. P5 instances also provide 3200 Gbps of aggregate network bandwidth with support for GPUDirect RDMA, enabling lower latency and efficient scale-out performance by bypassing the CPU on internode communication.

Here are the specs for these instances:

Instance
Size
vCPUs Memory
(GiB)
GPUs
(H100)
Network Bandwidth
(Gbps)
EBS Bandwidth
(Gbps)
Local Storage
(TB)
P5.48xlarge 192 2048 8 3200 80 8 x 3.84

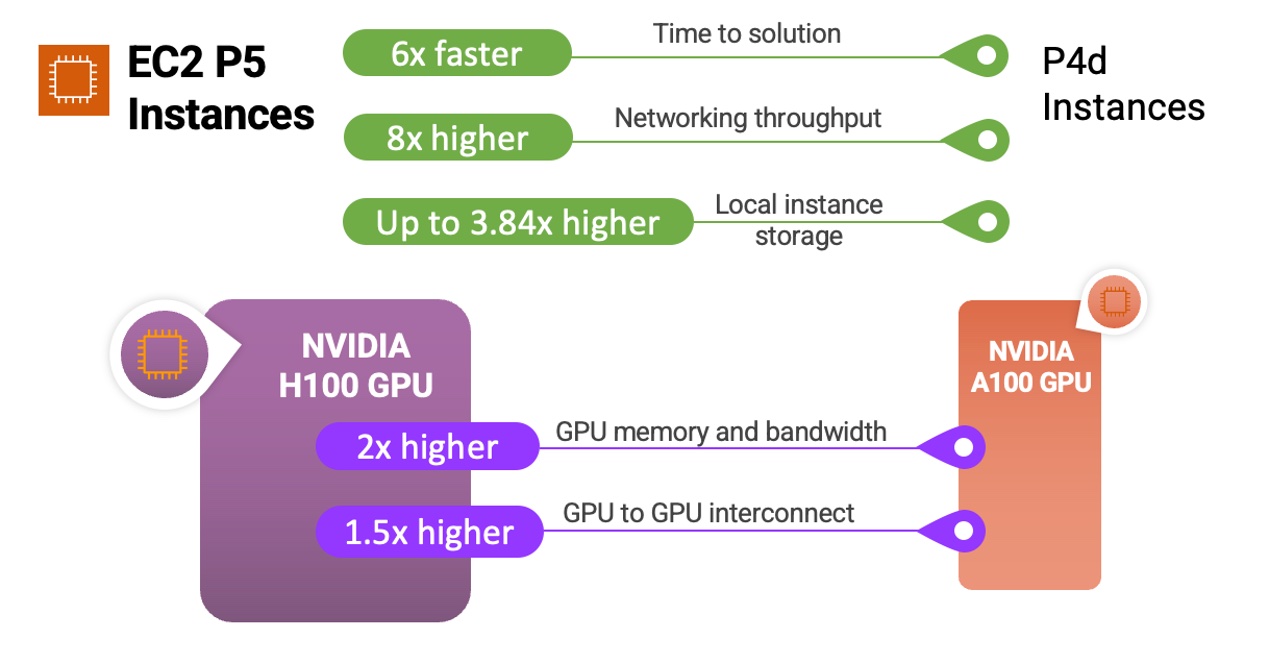
Here’s a quick infographic that shows you how the P5 instances and NVIDIA H100 Tensor Core GPUs compare to previous instances and processors:

P5 instances are ideal for training and running inference for increasingly complex LLMs and computer vision models behind the most demanding and compute-intensive generative AI applications, including question answering, code generation, video and image generation, speech recognition, and more. P5 will provide up to 6 times lower time to train compared with previous generation GPU-based instances across those applications. Customers who can use lower precision FP8 data types in their workloads, common in many language models that use a transformer model backbone, will see further benefit at up to 6 times performance increase through support for the NVIDIA transformer engine.

HPC customers using P5 instances can deploy demanding applications at greater scale in pharmaceutical discovery, seismic analysis, weather forecasting, and financial modeling. Customers using dynamic programming (DP) algorithms for applications like genome sequencing or accelerated data analytics will also see further benefit from P5 through support for a new DPX instruction set.

This enables customers to explore problem spaces that previously seemed unreachable, iterate on their solutions at a faster clip, and get to market more quickly.

You can see the detail of instance specifications along with comparisons of instance types between p4d.24xlarge and new p5.48xlarge below:

Feature p4d.24xlarge p5.48xlarge Comparision
Number & Type of Accelerators 8 x NVIDIA A100 8 x NVIDIA H100 –
FP8 TFLOPS per Server – 16,000 640% vs.A100 FP16
FP16 TFLOPS per Server 2,496 8,000
GPU Memory 40 GB 80 GB 200%
GPU Memory Bandwidth 12.8 TB/s 26.8 TB/s 200%
CPU Family Intel Cascade Lake AMD Milan –
vCPUs 96  192 200%
Total System Memory 1152 GB 2048 GB 200%
Networking Throughput 400 Gbps 3200 Gbps 800%
EBS Throughput 19 Gbps 80 Gbps 400%
Local Instance Storage 8 TBs NVMe 30 TBs NVMe 375%
GPU to GPU Interconnect 600 GB/s 900 GB/s 150%

Second-generation Amazon EC2 UltraClusters and Elastic Fabric Adaptor
P5 instances provide market-leading scale-out capability for multi-node distributed training and tightly coupled HPC workloads. They offer up to 3,200 Gbps of networking using the second-generation Elastic Fabric Adaptor (EFA) technology, 8 times compared with P4d instances.

To address customer needs for large-scale and low latency, P5 instances are deployed in the second-generation EC2 UltraClusters, which now provide customers with lower latency across up to 20,000+ NVIDIA H100 Tensor Core GPUs. Providing the largest scale of ML infrastructure in the cloud, P5 instances in EC2 UltraClusters deliver up to 20 exaflops of aggregate compute capability.

EC2 UltraClusters use Amazon FSx for Lustre, fully managed shared storage built on the most popular high-performance parallel file system. With FSx for Lustre, you can quickly process massive datasets on demand and at scale and deliver sub-millisecond latencies. The low-latency and high-throughput characteristics of FSx for Lustre are optimized for deep learning, generative AI, and HPC workloads on EC2 UltraClusters.

FSx for Lustre keeps the GPUs and ML accelerators in EC2 UltraClusters fed with data, accelerating the most demanding workloads. These workloads include LLM training, generative AI inferencing, and HPC workloads, such as genomics and financial risk modeling.

Getting Started with EC2 P5 Instances
To get started, you can use P5 instances in the US East (N. Virginia) and US West (Oregon) Region.

When launching P5 instances, you will choose AWS Deep Learning AMIs (DLAMIs) to support P5 instances. DLAMI provides ML practitioners and researchers with the infrastructure and tools to quickly build scalable, secure distributed ML applications in preconfigured environments.

You will be able to run containerized applications on P5 instances with AWS Deep Learning Containers using libraries for Amazon Elastic Container Service (Amazon ECS) or Amazon Elastic Kubernetes Service  (Amazon EKS).  For a more managed experience, you can also use P5 instances via Amazon SageMaker, which helps developers and data scientists easily scale to tens, hundreds, or thousands of GPUs to train a model quickly at any scale without worrying about setting up clusters and data pipelines. HPC customers can leverage AWS Batch and ParallelCluster with P5 to help orchestrate jobs and clusters efficiently.

Existing P4 customers will need to update their AMIs to use P5 instances. Specifically, you will need to update your AMIs to include the latest NVIDIA driver with support for NVIDIA H100 Tensor Core GPUs. They will also need to install the latest CUDA version (CUDA 12), CuDNN version, framework versions (e.g., PyTorch, Tensorflow), and EFA driver with updated topology files. To make this process easy for you, we will provide new DLAMIs and Deep Learning Containers that come prepackaged with all the needed software and frameworks to use P5 instances out of the box.

Now Available
Amazon EC2 P5 instances are available today in AWS Regions: US East (N. Virginia) and US West (Oregon). For more information, see the Amazon EC2 pricing page. To learn more, visit our P5 instance page and explore AWS re:Post for EC2 or through your usual AWS Support contacts.

You can choose a broad range of AWS services that have generative AI built in, all running on the most cost-effective cloud infrastructure for generative AI. To learn more, visit Generative AI on AWS to innovate faster and reinvent your applications.

— Channy

How to scan EC2 AMIs using Amazon Inspector

Post Syndicated from Luke Notley original https://aws.amazon.com/blogs/security/how-to-scan-ec2-amis-using-amazon-inspector/

Amazon Inspector is an automated vulnerability management service that continually scans Amazon Web Services (AWS) workloads for software vulnerabilities and unintended network exposure. Amazon Inspector supports vulnerability reporting and deep inspection of Amazon Elastic Compute Cloud (Amazon EC2) instances, container images stored in Amazon Elastic Container Registry (Amazon ECR), and AWS Lambda functions. Operating system and programming language support is extensive, ranging from Bottlerocket to Windows Server.

Many customers use Amazon EC2 Auto Scaling groups as part of their resilience and scaling architecture for their workloads. With Auto Scaling groups, you can scale and deploy rapidly by using Amazon Machine Images (AMIs). However, AMIs within your environment can quickly become outdated as new vulnerabilities are discovered. A security best practice is to perform routine vulnerability assessments of your AMIs to identify whether newfound vulnerabilities apply to them. If you identify a vulnerability, you can update the AMI with the appropriate security patches, test the AMI in lower environments, and deploy the updated AMI in your environment. At this time, Amazon Inspector only supports scanning of running EC2 instances.

In this blog post, we’ll share a solution that you can use with Amazon EventBridge, AWS Lambda, AWS Step Functions, Amazon Simple Notification Service (Amazon SNS)­­, and Amazon Simple Storage Service (Amazon S3) to scan AMIs and generate Amazon Inspector finding reports to help ensure that your AMIs are scanned for known vulnerabilities and updated prior to deployment. Then, we will show you how to periodically scan selected EC2 AMIs based on a tagging strategy, and take automated actions.

Prerequisites

The solution provided in this post has a number of items that you will need to review and address before you deploy the solution:

  1. Make sure that the AMI to be scanned by Amazon Inspector is based from one of the operating systems that AWS supports for EC2 scanning.
  2. To successfully complete a scan, Amazon Inspector requires the EC2 instance to be a managed instance in AWS Systems Manager that has the Systems Manager Agent installed and running, and has an attached AWS Identity and Access Management (IAM) instance profile that allows Systems Manager to manage the instance. For more information, see Scanning Amazon EC2 instances with Amazon Inspector.
  3. If you use customer managed keys to encrypt Amazon Elastic Block Store (Amazon EBS) volumes and you have a default EC2 configuration set to encrypt EBS volumes, you will need to configure additional key policy permissions. For the customer managed key that encrypts EBS volumes, add the following example policy statement to the key policy. Make sure to replace <111122223333> with your own AWS account ID.
    {
                "Sid": "Allow use of the key by AMI Scanner State Machine",
                "Effect": "Allow",
                "Principal": {
                    "AWS": "arn:aws:iam:: <111122223333>:role/service-role/AMIScanner-Statemachine-role"
                },
                "Action": [
                    "kms:Encrypt",
                    "kms:Decrypt",
                    "kms:ReEncrypt*",
                    "kms:GenerateDataKey*",
                    "kms:DescribeKey"
                ],
                "Resource": "*"
            },

    If you don’t add this additional policy, the Step Functions state machine won’t allow the EC2 instances to launch. For more information, see Key policy sections that allow access to the customer managed key.

  4. The solution in this blog post requires that you activate Amazon Inspector in your AWS account. If you haven’t activated Amazon Inspector yet, learn more about the free trial and pricing, and follow the steps in the Amazon Inspector documentation to set up the service and start monitoring your account. Alternatively, you can activate Amazon Inspector by using the AWS Command Line Interface (AWS CLI) and this GitHub example.

Solution overview and architecture

In this solution, you will use the follow AWS services and features:

  • Task orchestration
    • AWS Step Functions state machine workflows are used in this solution to verify that conditions are successfully validated before moving to the next task. This helps ensure that the Amazon Inspector scanning of the temporary instance launched in the first state machine is completed before the second state machine starts. This can help reduce the overall cost of the solution and can help prevent the first state machine from reaching state transition limitations.
    • Lambda functions handle the logic for retrieving AMIs to be scanned, launching temporary instances, creating Amazon EventBridge rules, tagging AMIs, and exporting Amazon Inspector reports to Amazon S3.
  • AMI tagging
    • To use this solution, you need to tag the AMIs that Amazon Inspector will scan, because a Lambda function will use these tags to start the solution orchestration. For this post, we use the tag InspectorScan with a value of true. With AMI tagging, you can configure automated processes as part of your deployment pipelines to implement the tagging.
  • Storage of exported Amazon Inspector findings
    • Amazon S3 helps you store the exported Amazon Inspector findings report and use them in a standardized format for multiple use cases across AWS services, or use Amazon Athena to query the reports, which we will cover later in the post. Each scanned report is stored in the S3 bucket and is named in the form AMI-NAME/guid.JSON or AMI-NAME/guid.CSV, depending on the export format that you specify.
    • You can also use S3 event notifications to alert different operational teams that there are Amazon Inspector scan results that require review.
  • Encryption of Amazon Inspector findings reports
    • AWS Key Management Service (AWS KMS) is used to encrypt the findings report. The AWS KMS key used must be a customer managed, symmetric KMS encryption key, and importantly, the key must be in the same AWS Region as the S3 bucket that you configured to store the report. The solution in this post creates a new KMS key, as well as a key policy that is configured to grant permissions for Amazon Inspector to use the key.
  • Event tracking and scheduling
    • This solution uses an Amazon EventBridge rule to listen for completed Amazon Inspector scan events for each temporary EC2 instance launch. When the EventBridge rule finds a matched event, the rule passes the required parameters and invokes the second Step Functions state machine. The event pattern used in this solution uses the following format:
      	{
      			"source": ["aws.inspector2"],
      			"detail-type": ["Inspector2 Scan"],
      			"resources": ["i-abcdef01234567890"]
      		}

    • You can schedule the AMI scanning by using an EventBridge rule that invokes a Lambda function that runs on a schedule. The Lambda function uses a cron expression to occur weekly. You can configure this parameter according to your requirements. Initially, this rule will be disabled to allow you to configure and enable the rule at a later stage.
    • Amazon SNS sends notifications during the AMI scanning solution process. From the SNS topic, you can configure different subscriptions, depending on your preferred use case and environment. An example of a subscription could be a shared mailbox email address for the security team or incident ticketing system.

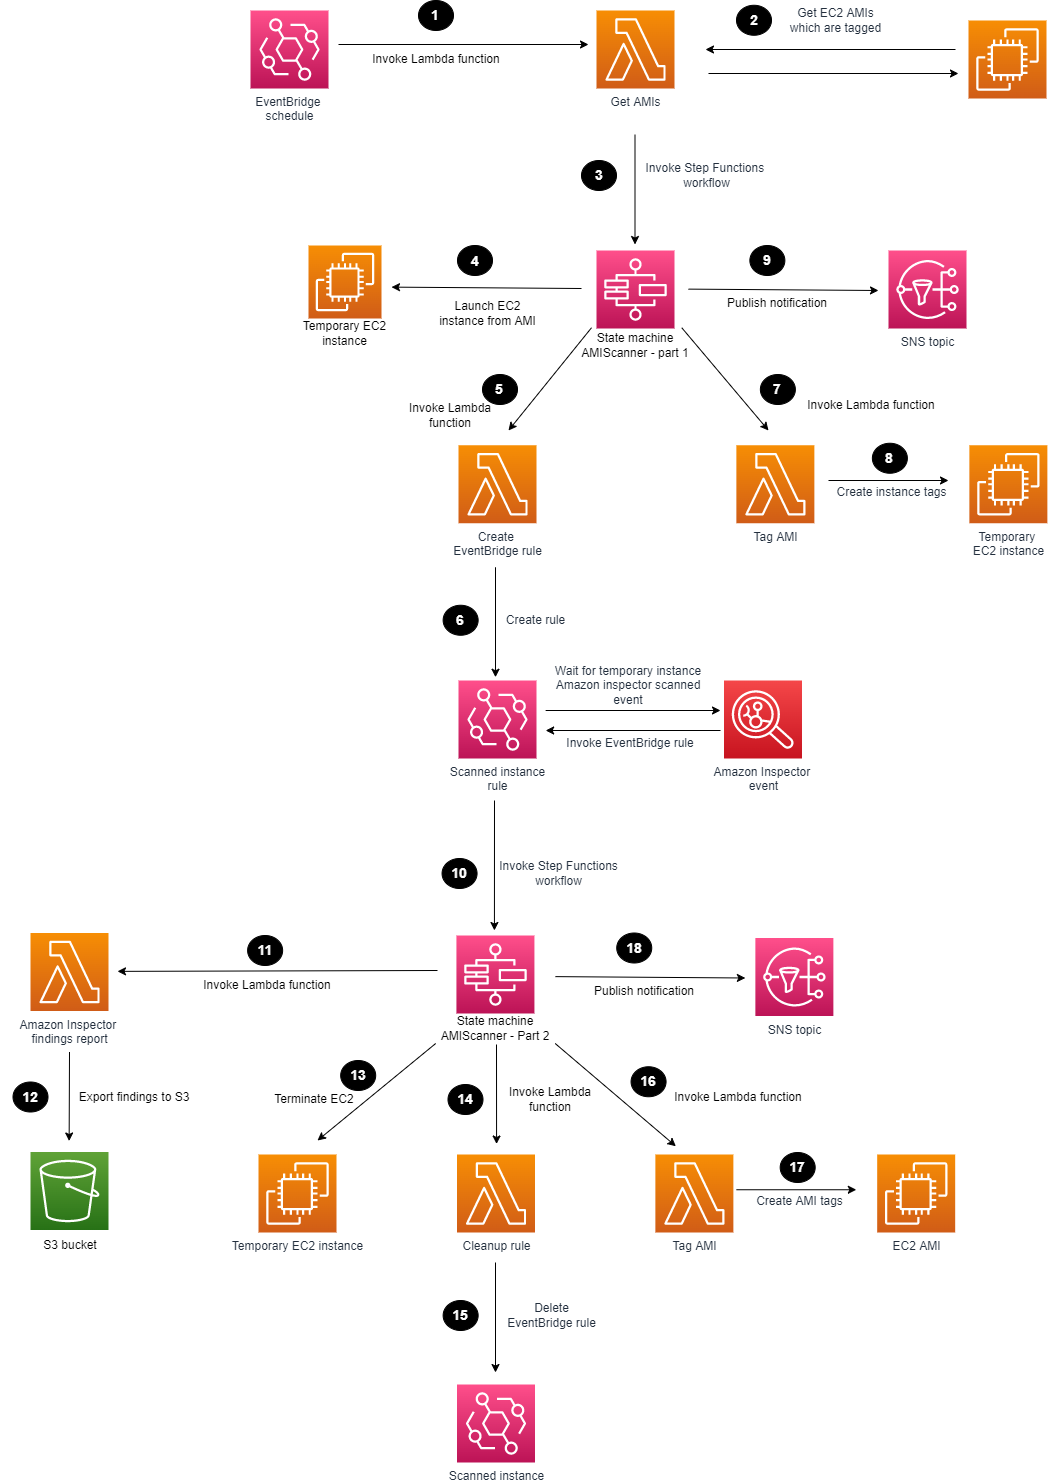
Figure 1 shows the solution architecture.

Figure 1: Amazon Inspector scanning of an AMI

Figure 1: Amazon Inspector scanning of an AMI

The high-level workflow of the solution is as follows:

  1. You can use EventBridge to create a scheduled rule to invoke a Lambda function. You can set the rule for daily, weekly, or monthly, depending on your use case.
  2. The Lambda function searches for AMIs with the appropriate tags and passes these as parameters to the Step Functions workflow.
  3. The first Step Functions state machine is invoked for each AMI to be scanned.
  4. The first Step Functions workflow deploys a temporary EC2 instance from the AMI that is defined.
  5. A Lambda function is invoked to create an EventBridge rule.
  6. An EventBridge rule is created to listen for the successful Amazon Inspector scanned event of the temporary EC2 instance.
  7. A Lambda function is invoked to tag the EC2 instance.
  8. The temporary EC2 instance is tagged, showing Amazon Inspector that scanning is in progress.
  9. The first Step Functions workflow sends a notification to an SNS topic.
  10. The EventBridge rule parses the required parameters and invokes the second Step Functions state machine.
  11. A Lambda function is invoked to generate an Amazon Inspector report and export the findings to an S3 bucket.
  12. The scanned Amazon Inspector AMI results are saved to an S3 bucket.
  13. The Step Functions workflow terminates the temporary EC2 instance that can reduce cost and clean up the process.
  14. A Lambda function is invoked to delete the temporary EventBridge rule.
  15. The temporary EventBridge rule and targets are deleted.
  16. A Lambda function is invoked to tag the AMI.
  17. The scanned AMI is updated with tagging metadata.
  18. The second Step Functions workflow sends a final notification to an SNS topic.

Deploy the solution

The solution will be deployed with the scheduled rule in Amazon EventBridge disabled to allow you to create your tagging strategy and to familiarize yourself with the solution. Later in this post, we’ll cover how to enable the Amazon EventBridge scheduled rule.

Step 1: Deploy the CloudFormation template

For this next step, make sure that you deploy the CloudFormation template provided for multi-AMI scanning in the AWS account and Region where you want to test this solution.

To deploy the CloudFormation template

  1. Choose the following Launch Stack button to launch a CloudFormation stack in your account. Note that the stack will launch in the N. Virginia (us-east-1) Region. To deploy this solution into other AWS Regions, download the solution’s CloudFormation template, modify it, and deploy it to the selected Region.

    Select this image to open a link that starts building the CloudFormation stack

    Make sure that you configure the following parameters in the CloudFormation template so that it deploys successfully:

    • AMITagName — The AMI tag name to check if the AMI should be scanned by Amazon Inspector.
    • AMITagValue — The AMI tag value to check if the AMI should be scanned by Amazon Inspector.
    • InspectorReportFormat — The report format, which can be either CSV or JSON.
    • InstanceSubnetID — The subnet ID to launch the temporary EC2 instance into.
    • InstanceType — The instance type to deploy the AMI to for temporary scanning purposes.
    • KmsKeyAdministratorRole — The existing IAM role that needs to have administrator access to the KMS key created for the solution. This key provides access to encrypt and decrypt the Amazon Inspector report.
    • S3ReportBucketName — The name of the S3 bucket to be created.
    • SnsTopic — The name of the new SNS topic to be created. This name defines the SNS topic that notifications are published to.
  2. Review the stack name and the parameters for the template.
  3. On the Quick create stack screen, scroll to the bottom and select I acknowledge that AWS CloudFormation might create IAM resources.
  4. Choose Create stack. The deployment of the CloudFormation stack will take 3–4 minutes.

After the CloudFormation stack has deployed successfully, you can use the deployed solution.

Step 2: Manually run the first Step Functions workflow

The first Step Functions state machine requires parameters to be passed in; the SingleAMI Lambda function accomplishes this. You can start the Lambda function by creating a test event and passing the correct JSON text and parameters. The following parameters are available in the output section of the CloudFormation stack that the solution deployed:

  • AmiId — The ID of the AMI to be used for deploying the EC2 instance. This is the EC2 AMI to be scanned.
  • EC2InstanceProfile — The Amazon Resource Name (ARN) of the EC2 instance profile that the CloudFormation stack created.
  • InstanceType — The type of EC2 instance to use for deployment.
  • KmsKeyName — The ARN of the KMS key to be used for encrypting and decrypting the Amazon Inspector report that the CloudFormation stack created.
  • S3Bucket — The name of the S3 bucket to which the Amazon Inspector reports will be exported. The S3 bucket was created previously by the CloudFormation stack.
  • S3ReportFormat — The report format that Amazon Inspector will use to export the findings report; either the JSON or the CSV format is valid.
  • SnsTopc — The ARN of the SNS topic to which notifications will be sent. This SNS topic was created previously by the CloudFormation stack.
  • StateMachineArn — The ARN of the first Step Functions state machine, which the Lambda function will run first.
  • SubnetId — The ID of the VPC subnet to which the EC2 instance will be attached and launched into. This is a required parameter and could be a subnet that is created specifically for this scanning purpose.

The following is an example parameter configuration and JSON that you can use to run the Lambda function. Make sure to replace each <user input placeholder> with your own information.

{
"AmiId" : "<AMI-ABCDEF01234567890>",
"Ec2InstanceProfile" : "arn:aws:iam::<111122223333>:instance-profile/Ec2InstanceLaunchRole",
"InstanceType" : "t3.medium",
"KMSKeyName" : "arn:aws:kms:region-name:<111122223333>:key/<a1b2c3d4-5678-90ab-cdef-EXAMPLE11111>",
"S3Bucket" : "<DOC-EXAMPLE-BUCKET-111122223333>",
"S3ReportFormat" : "CSV",
"SnsTopic" : "arn:aws:sns:region-name-2:<111122223333>:InspectorScanner",
"StateMachine": "arn:aws:states:region-name:<111122223333>:stateMachine:AMIScanner-Part1-LaunchEC2",
"SubnetId" : "<SUBNET-ABCDEF01234567890>"
}

After the first state machine is finished, the EventBridge rule listens for the successful Amazon Inspector scan event. An SNS notification is sent, similar to the following.


{"AWS Inspector AMI Scan status":"EC2 instance","For AMI":"ami-abcdef01234567890","Temporarily launched AMI using instance":"i-abcdef01234567890"}

After Amazon Inspector has finished scanning the EC2 instance, and the second state machine completes successfully, the Amazon Inspector finding report appears in the S3 bucket and notifications appear on the SNS topic that was created. The following is an example of an SNS notification.


{"AWS Inspector AMI Scan completed":"Successfully","For AMI":"ami-abcdef01234567890","AWS Inspector report located at S3 Bucket":"DOC-EXAMPLE-BUCKET-111122223333","Temporarily launched AMI using instance":"i-abcdef01234567890"}

Enable scheduled scanning

You can enable the EventBridge scheduled rule to handle multiple AMIs and automatic scheduling. The scheduled rule invokes a Lambda function on a scheduled basis that identifies AMIs with the appropriate tags and passes parameters to the Step Functions workflow.

To enable the rule

  • In the EventBridge rules console, navigate to AMIScanner-ScheduledSolutionTask, and choose Enable.
    Figure 2: Enable Amazon EventBridge scheduled rule

    Figure 2: Enable Amazon EventBridge scheduled rule

Extend the solution

With Amazon Athena, you can run SQL queries on raw data that is stored in S3 buckets. The Amazon Inspector reports are exported to S3, and you can query the data and create tables by using AWS Glue crawlers. To make sure that AWS Glue can crawl the S3 data, you need to add the role that you create for AWS Glue to the AWS KMS key permissions, so that AWS Glue can decrypt the S3 data. The following is an example policy JSON that you can update. Make sure to replace the AWS account ID <111122223333> and S3 bucket name <DOC-EXAMPLE-BUCKET-111122223333> with your own information.

{
"Sid": "Allow the AWS Glue crawler usage of the KMS key",
"Effect": "Allow",
"Principal": {
"AWS": "arn:aws:iam::<111122223333>:role/service-role/AWSGlueServiceRole-S3InspectorReports"
},
"Action": [
"kms:Decrypt",
"kms:GenerateDataKey*"
],
"Resource": "arn:aws:s3:::<DOC-EXAMPLE-BUCKET-111122223333>"
},

After an AWS Glue Data Catalog has been built, you can run the crawler on a scheduled basis to help keep the catalog up to date with the latest Amazon Inspector findings as they are exported into the S3 bucket.

Using Amazon Athena, you can run queries against the Amazon Inspector reports to generate output data that is relevant to your environment. For example, to list the AMIs that are affected by high-severity findings, you can run the following SQL query. Make sure to replace <DOC-EXAMPLE-BUCKET-111122223333> with your own information.

SELECT DISTINCT partition_0 from "<DOC-EXAMPLE-BUCKET-111122223333>" where severity='HIGH'

With the results, you can use AWS Systems Manager to update the relevant AMIs to include the latest patches and update the launch template used in your Auto Scaling groups.

To further extend this solution, you can also use Amazon QuickSight to visualize the data by connecting to the AWS Glue table and producing dashboards for consumption.

Conclusion

By performing security assessments of your AMIs on a regular basis, you can gain greater visibility and control over the security of your EC2 instances that are created from those AMIs. In this blog post, you learned how to set up AMI vulnerability assessments, and how the results of these continuous vulnerability assessments can help you keep your environment up to date with security patches. For additional hands-on walkthroughs for Amazon Inspector, see Amazon Inspector workshops. You can find the code for this blog post in the inspector-ami-scanning-solution GitHub repository.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Luke Notley

Luke Notley

Luke is a Senior Solutions Architect with Amazon Web Services and is based in Western Australia. Luke has a passion for helping customers connect business outcomes with technology and assisting customers throughout their cloud journey, helping them design scalable, flexible, and resilient architectures. In his spare time, he enjoys traveling, coaching basketball teams, and DJing.

Mixing AWS Graviton with x86 CPUs to optimize cost and resiliency using Amazon EKS

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/mixing-aws-graviton-with-x86-cpus-to-optimize-cost-and-resilience-using-amazon-eks/

This post is written by Yahav Biran, Principal SA, and Yuval Dovrat, Israel Head Compute SA.

This post shows you how to integrate AWS Graviton-based Amazon EC2 instances into an existing Amazon Elastic Kubernetes Service (Amazon EKS) environment running on x86-based Amazon EC2 instances. Customers use mixed-CPU architectures to enable their application to utilize a wide selection of Amazon EC2 instance types and improve overall application resilience. In order to successfully run a mixed-CPU application, it is strongly recommended that you test application performance in a test environment before running production applications on Graviton-based instances. You can follow AWS’ transition guide to learn more about porting your application to AWS Graviton.

This example shows how you can use KEDA for controlling application capacity across CPU types in EKS. KEDA will trigger a deployment based on the application’s response latency as measured by the Application Load Balancer (ALB). To simplify resource provisioning, Karpenter, an open-source Kubernetes node provisioning software, and AWS Load Balancer Controller, are shown as well.

Solution Overview

There are two solutions that this post covers to test a mixed-CPU application. The first configuration (shown in Figure 1 below) is the “A/B Configuration”. It uses an Application Load Balancer (ALB)-based Ingress to control traffic flowing to x86-based and Graviton-based node pools. You use this configuration to gradually migrate a live application from x86-based instances to Graviton-based instances, while validating the response time with Amazon CloudWatch.

A/B Configuration, with ALB ingress for gradual transition between CPU types

Figure 1, config 1: A/B Configuration

In the second configuration, the “Karpenter Controlled Configuration” (shown in Figure 2 below as Config 2), Karpenter automatically controls the instance blend. Karpenter is configured to use weighted provisioners with values that prioritize AWS Graviton-based Amazon EC2 instances over x86-based Amazon EC2 instances.

Karpenter Controlled Configuration, with Weighting provisioners topology

Figure 2, config II:  Karpenter Controlled Configuration, with Weighting provisioners topology

It is recommended that you start with the “A/B” configuration to measure the response time of live requests. Once your workload is validated on Graviton-based instances, you can build the second configuration to simplify the deployment configuration and increase resiliency. This enables your application to automatically utilize x86-based instances if needed, for example, during an unplanned large-scale event.

You can find the step-by-step guide on GitHub to help you to examine and try the example app deployment described in this post. The following provides an overview of the step-by-step guide.

Code Migration to AWS Graviton

The first step is migrating your code from x86-based instances to Graviton-based instances. AWS has multiple resources to help you migrate your code. These include AWS Graviton Fast Start Program, AWS Graviton Technical Guide GitHub Repository, AWS Graviton Transition Guide, and Porting Advisor for Graviton.

After making any required changes, you might need to recompile your application for the Arm64 architecture. This is necessary if your application is written in a language that compiles to machine code, such as Golang and C/C++, or if you need to rebuild native-code libraries for interpreted/JIT compiled languages such as the Python/C API or Java Native Interface (JNI).

To allow your containerized application to run on both x86 and Graviton-based nodes, you must build OCI images for both the x86 and Arm64 architectures, push them to your image repository (such as Amazon ECR), and stitch them together by creating and pushing an OCI multi-architecture manifest list. You can find an overview of these steps in this AWS blog post. You can also find the AWS Cloud Development Kit (CDK) construct on GitHub to help get you started.

To simplify the process, you can use a Linux distribution package manager that supports cross-platform packages and avoid platform-specific software package names in the Linux distribution wherever possible. For example, use:

RUN pip install httpd

instead of:

ARG ARCH=aarch64 or amd64
RUN yum install httpd.${ARCH}

This blog post shows you how to automate multi-arch OCI image building in greater depth.

Application Deployment

Config 1 – A/B controlled topology

This topology allows you to migrate to Graviton while validating the application’s response time (approximately 300ms) on both x86 and Graviton-based instances. As shown in Figure 1, this design has a single Listener that forwards incoming requests to two Target Groups. One Target Group is associated with Graviton-based instances, while the other Target Group is associated with x86-based instances. The traffic ratio associated with each target group is defined in the Ingress configuration.

Here are the steps to create Config 1:

  1. Create two KEDA ScaledObjects that scale the number of pods based on the latency metric (AWS/ApplicationELB-TargetResponseTime) that matches the target group (triggers.metadata.dimensionValue). Declare the maximum acceptable latency in targetMetricValue:0.3.
    Below is the Graviton deployment scaledObject (spec.scaleTargetRef), note the comments that denote the value of the x86 deployment scaledObject
apiVersion: keda.sh/v1alpha1
kind: ScaledObject
…
spec:
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: armsimplemultiarchapp #amdsimplemultiarchapp
…
  triggers:                 
    - type: aws-cloudwatch
      metadata:
        namespace: "AWS/ApplicationELB"
        dimensionName: "LoadBalancer"
        dimensionValue: "app/simplemultiarchapp/xxxxxx"
        metricName: "TargetResponseTime"
        targetMetricValue: "0.3"
  1. Once the topology has been created, add Amazon CloudWatch Container Insights to measure CPU, network throughput, and instance performance.
  2. To simplify testing and control for potential performance differences in instance generations, create two dedicated Karpenter provisioners and Kubernetes Deployments (replica sets) and specify the instance generation, CPU count, and CPU architecture for each one. This example uses c7g (Graviton3) and c6i (Intel) . You will remove these constraints in the next topology to allow more allocation flexibility.

The x86-based instances Karpenter provisioner:

apiVersion: karpenter.sh/v1alpha5
kind: Provisioner
metadata:
  name: x86provisioner
spec:
  requirements:
  - key: karpenter.k8s.aws/instance-generation
    operator: In
    values:
    - "6"
  - key: karpenter.k8s.aws/instance-cpu
    operator: In 
    values:
    - "2"
  - key: kubernetes.io/arch
    operator: In
    values:
    - amd64

The Graviton-based instances Karpenter provisioner:

apiVersion: karpenter.sh/v1alpha5
kind: Provisioner
metadata:
  name: arm64provisioner
spec:
  requirements:
  - key: karpenter.k8s.aws/instance-generation
    operator: In
    values:
    - "7"
  - key: karpenter.k8s.aws/instance-cpu
    operator: In
    values:
    - "2"
  - key: kubernetes.io/arch
    operator: In
    values:
    - arm64
  1. Create two Kubernetes Deployment resources—one per CPU architecture—that use nodeSelector to schedule one Deployment on Graviton-based instances, and another Deployment on x86-based instances. Similarly, create two NodePort Service resources, where each Service points to its architecture-specific ReplicaSet.
  2. Create an Application Load Balancer using the AWS Load Balancer Controller to distribute incoming requests among the different pods. Control the traffic routing in the ingress by adding an ingress.kubernetes.io/actions.weighted-routing annotation. You can adjust the weight in the example below to meet your needs. This migration example started with a 100%-to-0% x86-to-Graviton ratio, adjusting over time by 10% increments until it reached a 0%-to-100% x86-to-Graviton ratio.
…
alb.ingress.kubernetes.io/actions.weighted-routing: | 
{
…
  "targetGroups":[
    {
      "serviceName":"armsimplemultiarchapp-svc",
      "servicePort":"80","weight":50
    },
    {
      "serviceName":"amdsimplemultiarchapp-svc",
      "servicePort":"80","weight":50}]
    }
 }

spec:
  ingressClassName: alb
  rules:
    - http:
        paths:
          - path: /
            pathType: Prefix
            backend:
              service:
                name: weighted-routing

You can simulate live user requests to an example application ALB endpoint. Amazon CloudWatch populates ALB Target Group request/second metrics, dimensioned by HTTP response code, to help assess the application throughput and CPU usage.

During the simulation, you will need to verify the following:

  • Both Graviton-based instances and x86-based instances pods process a variable amount of traffic.
  • The application response time (p99) meets the performance requirements (300ms).

The orange (Graviton) and blue (x86) curves of HTTP 2xx responses (figure 4) show the application throughput (HTTP requests/seconds) for each CPU architecture during the migration.

Gradual transition from x86 to Graviton using ALB ingress

Figure 3 HTTP 2XX per CPU architecture

Figure 4 shows an example of application response time during the transition from x86-based instances to Graviton-based instances. The latency associated with each instance family grows and shrinks as the live request simulation changes the load on the application. In this example, the latency on x86 instances (until 07:00) grew up to 300ms because most of the request load was directed at to x86-based pods. It began to converge at around 08:00 when more pods were powered by Graviton-based instances. Finally, after 15:00, the request load was processed by Graviton-based instances entirely.

Two curves with different colors indicate p99 application targets response time. Graviton-based pods have a response time (between 150 and 300ms) similar to x86-based pods.

Figure 4: Target Response Time p99

Config 2 – Karpenter Controlled Configuration

After fully testing the application on Graviton-based EC2 instances, you are ready to simplify the deployment topology with weighted provisioners while preserving the ability to launch x86-based instances as needed.

Here are the steps to create Config 2:

  1. Reuse the CPU-based provisioners from the previous topology, but assign a higher .spec.weight to Graviton-based instances provisioner. The x86 provisioner is still deployed in case x86-based instances are required. The karpenter.k8s.aws/instance-family can be expanded beyond those set in Config 1 or excluded by switching the operator to NotIn.

The x86-based Amazon EC2 instances Karpenter provisioner:

apiVersion: karpenter.sh/v1alpha5
kind: Provisioner
metadata:
  name: x86provisioner
spec:
  requirements:
  - key: kubernetes.io/arch
    operator: In
    values: [amd64]

The Graviton-based Amazon EC2 instances Karpenter provisioner:

apiVersion: karpenter.sh/v1alpha5
kind: Provisioner
metadata:
  name: priority-arm64provisioner
spec:
  weight: 10
  requirements:
  - key: kubernetes.io/arch
    operator: In
    values: [arm64]
  1. Next, merge the two Kubernetes deployments into one deployment similar to the original before migration (i.e., no specific nodeSelector that points to a CPU-specific provisioner).

The two services are also combined into a single Kubernetes service and the actions.weighted-routing annotation is removed from the ingress resources:

spec:
  rules:
    - http:
        paths:
          - path: /app
            pathType: Prefix
            backend:
              service:
                name: simplemultiarchapp-svc
  1. Unite the two KEDA ScaledObject resources from the first configuration and point them to a single deployment, e.g., simplemultiarchapp. The new KEDA ScaledObject will be:
apiVersion: keda.sh/v1alpha1
kind: ScaledObject
metadata:
  name: simplemultiarchapp-hpa
  namespace: default
spec:
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: simplemultiarchapp
…

Two curves with different colors to indicate HTTP request/sec count. The curves show Graviton (Blue) as baseline and bursting with x86 (Orange).

Figure 5 Config 2 – Weighting provisioners results

A synthetic limit on Graviton CPU capacity is set to illustrate the scaling to x86_64 CPUs (Provisioner.limits.resources.cpu). The total application throughput (figure 6) is shown by aarch64_200 (blue) and x86_64_200 (orange). Mixing CPUs did not impact the target response time (Figure 6). Karpenter behaved as expected: prioritizing Graviton-based instances, and bursting to x86-based Amazon EC2 instances when CPU limits were crossed.

Mixing CPU did not impact the application latency when x86 instances where added

Figure 6 Config 2 -HTTP response time p99 with mixed-CPU provisioner

Conclusion

The use of a mixed-CPU architecture enables your application to utilize a wide selection of Amazon EC2 instance types and improves your applications’ resilience while meeting your service-level objectives. Application metrics can be used to control the migration with AWS ALB Ingress, Karpenter, and KEDA. Moreover, AWS Graviton-based Amazon EC2 instances can deliver up to 40% better price performance than x86-based Amazon EC2 instances. Learn more about this example on GitHub and more announcements about Gravtion.

Validating attestation documents produced by AWS Nitro Enclaves

Post Syndicated from maceneff original https://aws.amazon.com/blogs/compute/validating-attestation-documents-produced-by-aws-nitro-enclaves/

This blog post is written by Paco Gonzalez Senior EMEA IoT Specialist SA.

AWS Nitro Enclaves offers an isolated, hardened, and highly constrained environment to host security-critical applications. Think of AWS Nitro Enclaves as regular Amazon Elastic Compute Cloud (Amazon EC2) virtual machines (VMs) but with the added benefit of the environment being highly constrained.

A great benefit of using AWS Nitro Enclaves is that you can run your software as if it was a regular EC2 instance, but with no persistent storage and limited access to external systems. The only way to communicate with AWS Nitro Enclaves is using a VSOCK socket. This special type of communication mechanism acts as an isolated communication channel between the parent EC2 instance and AWS Nitro Enclaves.Diagram that shows how Nitro Enclaves uses the proven isolation of the Nitro Hypervisor to further isolate the CPU and memory of the Nitro Enclaves from users, applications, and libraries on the parent instance.

 Fig 1 – AWS Nitro Enclaves uses the proven isolation of the Nitro Hypervisor to further isolate the CPU and memory of the Nitro Enclaves from users, applications, and libraries on the parent instance.

AWS Nitro Enclaves comes with a custom Linux device called the Nitro Security Module (NSM), which is accessible via /dev/nsm. This device provides attestation capability to the Nitro Enclaves. The attestation comes in the form of an attestation document. The attestation document makes it easy and safe to build trust between systems that interact with the Nitro Enclaves. The external system must have a mechanism to process the attestation document to determine the validity of the attestation document.

In this post, I go through the anatomy of an attestation document produced by the NSM API. I then show you an example of how to perform different validations that help determine the accuracy of an attestation document produced by the AWS Nitro Enclaves Security Module. I use syntactic and semantic validations to check for the attestation document’s correctness before proceeding with a cryptographic validation of the contents of the document’s payload. The examples used in this post use the C language. Look at the companion repository available in GitHub for access to the all source code used in this post.

Anatomy of an attestation document produced by AWS Nitro Enclaves

The attestation document uses the Concise Binary Object Representation (CBOR) format to encode the data. The CBOR object is wrapped using the CBOR Object Signing and Encryption (COSE) protocol. The COSE format used is a single-signer data structure called “COSE_Sign1”. The object is comprised of headers, the payload, and a signature.

For more information about COSE, see RFC 8152: CBOR Object Signing and Encryption (COSE). For more information about CBOR, see RFC 8949 Concise Binary Object Representation (CBOR).

We published a library to make it easy to interact with the NSM. The library contains helpers which your application, running on the Nitro Enclaves, can use to communicate with the NSM device.

Here is the minimum code needed to generate an attestation document:

#include <stdlib.h>
#include <stdio.h>
#include <nsm.h>

#define NSM_MAX_ATTESTATION_DOC_SIZE (16 * 1024)

int main(void) {

    /// NSM library initialization function.  
    /// *Returns*: A descriptor for the opened device file.

    int nsm_fd = nsm_lib_init();
    if (nsm_fd < 0) {
        exit(1);
    }

    /// NSM `GetAttestationDoc` operation for non-Rust callers.  
    /// *Argument 1 (input)*: The descriptor to the NSM device file.  
    /// *Argument 2 (input)*: User data.  
    /// *Argument 3 (input)*: The size of the user data buffer.  
    /// *Argument 4 (input)*: Nonce data.  
    /// *Argument 5 (input)*: The size of the nonce data buffer.  
    /// *Argument 6 (input)*: Public key data.  
    /// *Argument 7 (input)*: The size of the public key data buffer.  
    /// *Argument 8 (output)*: The obtained attestation document.  
    /// *Argument 9 (input / output)*: The document buffer capacity (as input)
    /// and the size of the received document (as output).  
    /// *Returns*: The status of the operation.

    int status;
    uint8_t att_doc_buff[NSM_MAX_ATTESTATION_DOC_SIZE];
    uint32_t att_doc_cap_and_size = NSM_MAX_ATTESTATION_DOC_SIZE;

    status = nsm_get_attestation_doc(nsm_fd, NULL, 0, NULL, 0, NULL, 0, att_doc_buff, 
                                    &att_doc_cap_and_size);
    if (status != ERROR_CODE_SUCCESS) {
        printf("[Error] Request::Attestation got invalid response: %s\n",status);
        exit(1);
    }

    printf("########## attestation_document_buff ##########\r\n");
    for(int i=0; i<att_doc_cap_and_size; i++)
        fprintf(stdout, "%02X", att_doc_buff[i]);

    exit(0);
}

To produce a sample attestation document, initialize the device, call the function ‘nsm_get_attestation_doc’ inside the AWS Nitro Enclaves, and dump the contents. The library is written using Rust, but it contains
bindings for C. You can read more about the library and some of the other relevant capabilities
here.

The COSE headers contain a protected and an un-protected data section. The cryptographic algorithm used for the signature is specified inside the protected area. AWS Nitro Enclaves use a 384-bit elliptic curve algorithm (P-384) to sign attestation documents. AWS Nitro Enclaves do not use the unprotected data field so it is always left blank.

The payload contains fixed parameters that include the following: information about the issuing NSM, a timestamp of the issuing event, a map of all the locked Platform Configuration Registers (PCRs) at the moment the attestation document was generated, the hashing algorithm used to produce the digest that was used to calculate the PCR values – AWS Nitro Enclaves use a 384 bit secure hashing algorithm (SHA384), a x509 certificate signed by AWS Nitro Enclaves’ Private Public Key Infrastructure (PKI). An AWS Nitro Enclaves certificate expires three hours after it has been issued. The common name (CN) contains information about the issuing NSM – and finally the issuing Certificate Authority (CA) bundle. The payload also contains optional parameters that a third-party application can use to create custom authentication and authorization workflows. The optional parameters are: a public key, a cryptographic nonce, and additional arbitrary data.

Finally, the signature is the result of a signing operation using the private key related to the public key contained inside the certificate that is part of the payload.

Diagram that illustrates the components of a attestation document produced by a Nitro Enclave

Fig 2. An attestation document is generated and signed by the Nitro Hypervisor. It contains information about the Nitro Enclaves and it can be used by an external service to verify the identity of Nitro Enclaves and to establish trust. You can use the attestation document to build your own cryptographic attestation mechanisms.

Syntactical validation

Early validation of the attestation document format makes sure that only documents that conform to the expected structure are processed in subsequent steps.

I start by attempting to decode the CBOR object and testing to see if it corresponds to a COSE object signed with one signer or ‘COSE_Sign1’ structure. This can be easily done by looking at the most significant first three bits (MSB) of the first byte – I am expecting a stream of CBOR bytes (decimal 6). Then, I take the least significant (LSB) remaining five bits of the first byte – I am expecting a tag that tells me it is a COSE_Sign1 object (decimal 18).

assert(att_doc_buff[0*] == 6 <<5 | 18); // 0xD2

* Note that the time of writing, the NSM does not include the COSE tag and thus this validation cannot be made and is mentioned in this post for informational purposes only. However, it is important to keep this in mind, as the tag is part of the standard, and the NSM device or library could include it in the future.*

The next step is to parse the actual CBOR object. A COSE_Sign1 object is an array of size 4 (protected headers, un protected headers, payload, and signature). Therefore, I must check that the next three MSB correspond to Type 4 (array) and that the size is exactly 4.

assert(att_doc_buff[0] == 4 <<5 | 4); // 0x84

The next byte determines what the first CBOR item of the array looks like. I am expecting the protected COSE header as the first item of the array. The CBOR field should indicate that the contents of the item are of a Type 2 (raw bytes) and the size should be exactly 4.

assert(att_doc_buff[1] == 2 <<5 | 4); // 0x44

The next four bytes represent the protected header. The contents of this item is a regular CBOR object. The object should contain a Type 5 (map) with a single item (1). The item first key is expected to be the number 1. The first three MSB of the first byte should be a Type 1 (negative integer). The remaining five LSB should indicate that the value is an 8-bit number (decimal 24). The last byte should be negative 35 as it maps to the P-384 curve that Nitro Enclaves use. Note that CBOR negative numbers are stored minus 1.

assert(att_doc_buff[2] == 5 <<5 | 1); // 0xA1
assert(att_doc_buff[3] == 0x01); // 0x01
assert(att_doc_buff[4] == 1 <<5 | 24); // 0x38
assert(att_doc_buff[4] == 35-1); // 0x22

The next byte corresponds to the unprotected header. AWS Nitro Enclaves do not use unprotected headers. Therefore, the expected is a Type 5 (map) with zero items.

assert(att_doc_buff[6] == 5 <<5 | 0); // 0xA0

Now that I am done inspecting the headers, I can move onto the payload. The CBOR object used for the payload is Type 2 (raw bytes). This time we are expecting a large steam of bytes. The remaining five LSB are used to indicate the data type used to indicate the size of the byte stream (i.e. 8-bit, 16-bit). AWS Nitro Enclaves attestation documents are about 5 KiB without using any of the three optional parameters. The optional parameters have a size limit of 1 KiB each. This means that it would be highly unlikely for the buffer to be larger than a 16-bit number (CBOR short count: 25).

assert(att_doc_buff[8] == 2 <<5 | 25); // 0x59

The next two bytes represent the size of the payload which I am going to skip those for now, as the contents of the payload are validated in subsequent steps. I’ll move onto the final portion of the attestation document: the signature. The signature has to be a Type 2 (raw bytes) of exactly 96 bytes.

    uint16_t payload_size = att_doc_buff[8] << 8 | att_doc_buff[9];
    assert(att_doc_buff[9+payload_size+1] == (2<<5 | 24));   // 0x58
    assert(att_doc_buff[9+payload_size+1+1] == 96);         // 0x60

At this point, I have validated that the data produced by the NSM looks the way it should. My application is ready to start looking into the contents of the attestation document.

I want to make sure that the document contains all mandatory fields and I can check that the fields have the right structure and their sizes are within the expected boundaries. I have evidence that the data looks the way it should, so I am ready to use an off-the-shelf CBOR library to make the validation process easier instead of doing it by hand.

Here is an example of how to load a CBOR object using libcbor and standard C libraries to check the contents. I am showing just one example to illustrate the process. Refer to the section ‘Verifying the root of trust’ in the AWS Nitro Enclaves User Guide for a detailed description of each parameter and the validations that your application should perform to make sure that the document is valid.

#include <stdlib.h>
#include <stdio.h>
#include <string.h>
#include <assert.h>

#include <cbor.h>
#include <openssl/ssl.h>

#define APP_X509_BUFF_LEN                   (1024*2)
#define APP_ATTDOC_BUFF_LEN                 (1024*10)

void output_handler(char * msg){
    fprintf(stdout, "\r\n%s\r\n", msg);
}

void output_handler_bytes(uint8_t * buffer, int buffer_size){    
    for(int i=0; i<buffer_size; i++)
        fprintf(stdout, "%02X", buffer[i]);
    fprintf(stdout, "\r\n");
}

int read_file( unsigned char * file, char * file_name, size_t elements) {
    FILE * fp; size_t file_len = 0;
    fp = fopen(file_name, "r");
    file_len = fread(file, sizeof(char), elements, fp);
    if (ferror(fp) != 0 ) {
        fputs("Error reading file", stderr);
    } 
    fclose(fp);
    return file_len; 
}  

int main(int argc, char* argv[]) {

    // STEP 0 - LOAD ATTESTATION DOCUMENT

    // Check inputs, expect two
    if (argc != 3) { 
        fprintf(stderr, "%s\r\n", "ERROR: usage: ./main {att_doc_sample.bin} {AWS_NitroEnclaves_Root-G1.pem}"); exit(1);
    }

    // Load file into buffer, use 1st argument
    unsigned char * att_doc_buff = malloc(APP_ATTDOC_BUFF_LEN);
    int att_doc_len = read_file(att_doc_buff, argv[1], APP_ATTDOC_BUFF_LEN );

    // STEP 1 - SYTANCTIC VALIDATON

    // Check COSE TAG (skipping - not currently implemented by AWS Nitro Enclaves)
    // assert(att_doc_buff[0] == 6 <<5 | 18); // 0xD2
    // Check if this is an array of exactly 4 items
    assert(att_doc_buff[0] == (4<<5 | 4));      // 0x84
    // Check if next item is a byte stream of 4 bytes
    assert(att_doc_buff[1] == (2<<5 | 4));      // 0x44
    // Check is fist item if byte stream is a map with 1 item
    assert(att_doc_buff[2] == (5<<5 | 1));      // 0xA1
    // Check that the first key of the map is 0x01
    assert(att_doc_buff[3] == 0x01);            // 0x01
    // Check that value of the the first key of the map is -35 (P-384 curve)
    assert(att_doc_buff[4] == (1 <<5 | 24));    // 0x38
    assert(att_doc_buff[5] == 35-1);            // 0x22
    // Check that next item is a map of 0 items
    assert(att_doc_buff[6] == (5<<5 | 0));      // 0xA0
    // Check that the next item is a byte stream and the size is a 16-bit number (dec. 25)
    assert(att_doc_buff[7] == (2<<5 | 25));     // 0x59
    // Cast the 16-bit number
    uint16_t payload_size = att_doc_buff[8] << 8 | att_doc_buff[9];
    // Check that the item after the payload is a byte stream and the size is 8-bit number (dec. 24)
    assert(att_doc_buff[9+payload_size+1] == (2<<5 | 24));   // 0x58
    // Check that the size of the signature is exactly 96 bytes
    assert(att_doc_buff[9+payload_size+1+1] == 96);         // 0x60

    // Parse buffer using library
    struct cbor_load_result ad_result;
    cbor_item_t * ad_item = cbor_load(att_doc_buff, att_doc_len, &ad_result);
    free(att_doc_buff); // not needed anymore

    // Parse protected header -> item 0 
    cbor_item_t * ad_pheader = cbor_array_get(ad_item, 0); 
    size_t ad_pheader_len = cbor_bytestring_length(ad_pheader);

    // Parse signed bytes -> item 2 (skip un-protected headers as they are always empty)
    cbor_item_t * ad_signed = cbor_array_get(ad_item, 2);
    size_t ad_signed_len = cbor_bytestring_length(ad_signed);

    // Load signed bytes as a new CBOR object
    unsigned char * ad_signed_d = cbor_bytestring_handle(ad_signed);
    struct cbor_load_result ad_signed_result;
    cbor_item_t * ad_signed_item = cbor_load(ad_signed_d, ad_signed_len, &ad_signed_result);

    // Create the pair structure
    struct cbor_pair * ad_signed_item_pairs = cbor_map_handle(ad_signed_item);

    // Parse signature -> item 3
    cbor_item_t * ad_sig = cbor_array_get(ad_item, 3); 
    size_t ad_sig_len = cbor_bytestring_length(ad_sig);
    unsigned char * ad_sig_d = cbor_bytestring_handle(ad_sig);

    // Example 01: Check that the first item's key is the string "module_id" and that is not empty
    size_t module_k_len = cbor_string_length(ad_signed_item_pairs[0].key);
    unsigned char * module_k_str = realloc(cbor_string_handle(ad_signed_item_pairs[0].key), module_k_len+1); //null char
    module_k_str[module_k_len] = '\0';
    size_t module_v_len = cbor_string_length(ad_signed_item_pairs[0].value);
    unsigned char * module_v_str = realloc(cbor_string_handle(ad_signed_item_pairs[0].value), module_v_len+1); //null char
    module_v_str[module_v_len] = '\0';
    assert(module_k_len != 0);
    assert(module_v_len != 0);

    // Example 02: Check that the module id key is actually the string "module_id"
    assert(!strcmp("module_id",(const char *)module_k_str));

    // Example 03: Check that the signature is exactly 96 bytes long
    assert(ad_sig_len == 96);

    // Example 04: Check that the protected header is exactly 4 bytes long
    assert(ad_pheader_len == 4);

Semantic validation

The next step is to look at the data contained in the attestation document and check if it conforms to pre-defined business rules. The attestation document contains a certificate that was signed by the AWS Nitro Enclaves’ PKI. This validation it is important, as it proves that the document was signed by the AWS Nitro Enclaves’ PKI.

The signature of an x509 certificate is based on the certificate’s payload digest. Validating this signature means that I trust the information contained within the certificate, including the public key which I can later use to validate the attestation document itself. Furthermore, the information in the document contains details about the NSM module and a timestamp. Passing this check provides the assurances I need to trust that the document originated from my software running on AWS Nitro Enclaves at a specific time.

Diagram that illustrates the components of a x.509 certificate, part of the payload of a attestation document produced by AWS Nitro Enclaves.

Fig 3. The attestation document contains a x.509 certificate that was signed by the AWS Nitro Enclaves’ PKI.

Here is an example of how I use the AWS Nitro Enclaves’ Private PKI root certificate from an external file. Then, use the CA bundle contained in the attestation document to validate the authenticity of the certificate contained in the document. In this example, I am using the OpenSSL library.

// STEP 2 -  SEMANTIC VALIDATION

    // Load AWS Nitro Enclave's Private PKI root certificate
    unsigned char * x509_root_ca = malloc(APP_X509_BUFF_LEN);
    int x509_root_ca_len = read_file(x509_root_ca, argv[2], APP_X509_BUFF_LEN );
    BIO * bio = BIO_new_mem_buf((void*)x509_root_ca, x509_root_ca_len);
    X509 * caX509 = PEM_read_bio_X509(bio, NULL, NULL, NULL);
    if (caX509 == NULL) {
        fprintf(stderr, "%s\r\n", "ERROR: PEM_read_bio_X509 failed"); exit(1);
    }
    free(x509_root_ca); free(bio);
    // Create CA_STORE
    X509_STORE * ca_store = NULL;
    ca_store = X509_STORE_new();
    /* ADD X509_V_FLAG_NO_CHECK_TIME FOR TESTING! TODO REMOVE */
    X509_STORE_set_flags (ca_store, X509_V_FLAG_NO_CHECK_TIME);
    if (X509_STORE_add_cert(ca_store, caX509) != 1) {
        fprintf(stderr, "%s\r\n", "ERROR: X509_STORE_add_cert failed"); exit(1);
    }
    // Add certificates to CA_STORE from cabundle
    // Skip the first one [0] as that is the Root CA and we want to read it from an external source
    for (int i = 1; i < cbor_array_size(ad_signed_item_pairs[5].value); ++i){ 
        cbor_item_t * ad_cabundle = cbor_array_get(ad_signed_item_pairs[5].value, i); 
        size_t ad_cabundle_len = cbor_bytestring_length(ad_cabundle);
        unsigned char * ad_cabundle_d = cbor_bytestring_handle(ad_cabundle);
        X509 * cabnX509 = X509_new();
        cabnX509 = d2i_X509(&cabnX509, (const unsigned char **)&ad_cabundle_d, ad_cabundle_len);
        if (cabnX509 == NULL) {
            fprintf(stderr, "%s\r\n", "ERROR: d2i_X509 failed"); exit(1);
        }
        if (X509_STORE_add_cert(ca_store, cabnX509) != 1) {
            fprintf(stderr, "%s\r\n", "ERROR: X509_STORE_add_cert failed"); exit(1);
        }
    }

    // Load certificate from attestation dcoument - this a certificate that we don't trust (yet)
    size_t ad_signed_cert_len = cbor_bytestring_length(ad_signed_item_pairs[4].value);
    unsigned char * ad_signed_cert_d = realloc(cbor_bytestring_handle(ad_signed_item_pairs[4].value), ad_signed_cert_len);
    X509 * pX509 = X509_new();
    pX509 = d2i_X509(&pX509, (const unsigned char **)&ad_signed_cert_d, ad_signed_cert_len);
    if (pX509 == NULL) {
        fprintf(stderr, "%s\r\n", "ERROR: d2i_X509 failed"); exit(1);
    }
    // Initialize X509 store context and veryfy untrusted certificate
    STACK_OF(X509) * ca_stack = NULL;
    X509_STORE_CTX * store_ctx = X509_STORE_CTX_new();
    if (X509_STORE_CTX_init(store_ctx, ca_store, pX509, ca_stack) != 1) {
        fprintf(stderr, "%s\r\n", "ERROR: X509_STORE_CTX_init failed"); exit(1);
    }
    if (X509_verify_cert(store_ctx) != 1) {
        fprintf(stderr, "%s\r\n", "ERROR: X509_verify_cert failed"); exit(1);
    }
    fprintf(stdout, "%s\r\n", "OK: ########## Root of Trust Verified! ##########");

Having proof that the certificate was signed by the expected CA is just the beginning. I also want to make sure that the contents of the certificate are correct. This involves checking that the certificate has not expired, as well as making sure that the critical extensions contain correct information to name a few.

Cryptographic validation

The syntactic validation helped me determine that the attestation document has the right shape, and the sematic validation helped me determine if the document meets my business rules. However, I still don’t know for sure if the document is valid.

The attestation document contains critical information, such as PCRs and the AWS Identity Access and Management (IAM) role among other details. I can safely use these two values in my authentication or authorization workflows if I can prove that they are trustworthy.

The attestation document was signed using a private key that is never exposed. However, the corresponding public key is contained within the certificate that was issued and stored within the attestation document. I know I can trust the contents of this certificate because I have proof that the certificate was signed by an entity that I trust.

Here is an example where I cryptographically prove that all the protected contents of the attestation document are related to the public key contained in the certificate. To validate the COSE signature, I must first recreate the original message that was used during the signature operation – COSE uses a specific format. Then, I use OpenSSL to check if there is a match between the message, signature, and public key. If the signature checks, then I can trust the contents of the already semantically-verified payload.

 // STEP 3 - CRYPTOGRAPHIC VALIDATION

    #define SIG_STRUCTURE_BUFFER_S (1024*10)
    // Create new empty key
    EVP_PKEY * pkey = EVP_PKEY_new();
    // Create a new eliptic curve object using P-384 curve
    EC_KEY * ec_key = EC_KEY_new_by_curve_name(NID_secp384r1);
    // Reference the public key stucture and eliptic curve object with each other
    EVP_PKEY_assign_EC_KEY(pkey, ec_key);
    // Load the public key from the attestation document (we trust it now)
    pkey = X509_get_pubkey(pX509);
    if (pkey == NULL) {
        fprintf(stderr, "%s\r\n", "ERROR: X509_get_pubkey failed"); exit(1);
    }
    // Allocate, initialize and return a digest context
    EVP_MD_CTX * ctx = EVP_MD_CTX_create();
    // Set up verification context
    if (EVP_DigestVerifyInit(ctx, NULL, EVP_sha384(), NULL, pkey) <= 0) {
        fprintf(stderr, "%s\r\n", "ERROR: EVP_DigestVerifyInit failed"); exit(1);
    }
    // Recreate COSE_Sign1 structure, and serilise it into a buffer
    cbor_item_t * cose_sig_arr = cbor_new_definite_array(4);
    cbor_item_t * cose_sig_arr_0_sig1 = cbor_build_string("Signature1"); 
    cbor_item_t * cose_sig_arr_2_empty = cbor_build_bytestring(NULL, 0);

    assert(cbor_array_push(cose_sig_arr, cose_sig_arr_0_sig1));
    assert(cbor_array_push(cose_sig_arr, ad_pheader));
    assert(cbor_array_push(cose_sig_arr, cose_sig_arr_2_empty));
    assert(cbor_array_push(cose_sig_arr, ad_signed));

    unsigned char sig_struct_buffer[SIG_STRUCTURE_BUFFER_S];
    size_t sig_struct_buffer_len = cbor_serialize(cose_sig_arr, sig_struct_buffer, SIG_STRUCTURE_BUFFER_S);
    // Hash message and load it into the verificaiton context
    if (EVP_DigestVerifyUpdate(ctx, sig_struct_buffer, sig_struct_buffer_len) <= 0) {
        fprintf(stderr, "%s\r\n", "ERROR: nEVP_DigestVerifyUpdate failed"); exit(1);
    }
    // Create R and V BIGNUM structures
    BIGNUM * sig_r = BN_new(); BIGNUM * sig_v = BN_new();
    BN_bin2bn(ad_sig_d, 48, sig_r); BN_bin2bn(ad_sig_d + 48, 48, sig_v);
    // Allocate an empty ECDSA_SIG structure
    ECDSA_SIG * ec_sig = ECDSA_SIG_new();
    // Set R and V values
    ECDSA_SIG_set0(ec_sig, sig_r, sig_v);
    // Convert R and V values into DER format
    int sig_size = i2d_ECDSA_SIG(ec_sig, NULL);
    unsigned char * sig_bytes = malloc(sig_size); unsigned char * p;
    memset_s(sig_bytes,sig_size,0xFF, sig_size);
    p = sig_bytes;
    sig_size = i2d_ECDSA_SIG(ec_sig, &p);
    // Verify the data in the context against the signature and get final result
    if (EVP_DigestVerifyFinal(ctx, sig_bytes, sig_size) != 1) {
        fprintf(stderr, "%s\r\n", "ERROR: EVP_DigestVerifyFinal failed"); exit(1);
    } else {
        fprintf(stdout, "%s\r\n", "OK: ########## Message Verified! ##########"); 
        free(sig_bytes);
        exit(0);
    }
    //#endif

    exit(1);

}

Conclusion

In this post, I went through a detailed examination of attestation documents produced by the AWS Nitro Enclaves. Then, I went over different types of validations (syntactic, semantic, and cryptographic) that safely help determine if an attestation document should be trusted. I’ve also included access to a public repository that contains the source code used in this post. New AWS Nitro Enclaves users can use it as a starting point when looking to integrate their applications with AWS Nitro Enclaves and build highly secure and confidential solutions.

AWS Application Migration Service Major Updates: Global View, Import and Export from Local Disk, and Additional Post-launch Actions

Post Syndicated from Irshad Buchh original https://aws.amazon.com/blogs/aws/aws-application-migration-service-major-updates-global-view-import-and-export-from-local-disk-and-additional-post-launch-actions/

AWS Application Migration Service simplifies, expedites, and reduces the cost of migrating your applications to AWS. It allows you to lift and shift many physical, virtual, or cloud servers without compatibility issues, performance disruption, or long cutover windows. You can minimize time-intensive, error-prone manual processes by automating replication and conversion of your source servers from physical, virtual, or cloud infrastructure to run natively on AWS by using Application Migration Service for migration. Earlier this year, we introduced major improvements, such as a server migration metrics dashboard, import and export, and additional post-launch modernization actions.

Today, I’m pleased to announce three major updates to Application Migration Service. Here’s the quick summary for each feature release:

  • Global View – You can manage large-scale migrations across multiple accounts. This feature provides you both visibility and the ability to perform specific actions on source servers, apps, and waves in different AWS accounts.
  • Import and Export from Local Disk – You can now use Application Migration Service to import your source environment inventory list to the service from a CSV file on your local disk. You can also export your source server inventory list from the service to a CSV file and download it to your local disk. You can continue leveraging the previously launched import and export functionality to and from an S3 bucket.
  • Additional Post-launch Actions – In this update, Application Migration Service added four additional predefined post-launch actions. These actions are applied to your migrated applications when you launch them on AWS.

Let me share how you can use these features for your migration.

Global View
Global View provides you the visibility and the ability to perform specific actions on source servers, applications, and waves in different AWS accounts. Global view uses AWS Organizations to structure a management account (which has access to source servers in multiple member accounts) and member accounts (which only have access to their own source servers).

To use this feature, you need to have an AWS account in which AWS Application Migration Service is initialized. This account must be an admin in AWS Organizations or a delegated admin for AWS Application Migration Service. You can view the Global View page on the Application Migration Service page in the AWS Management Console by selecting Global View in the left navigation menu.

You can use the global view feature to see source servers, applications and waves across multiple managed accounts and perform various actions, including:

  • Launching test and cutover instances across accounts
  • Monitoring migration execution progress across accounts

The main Global View page provides an overview of your account and this information changes depending on whether you have a management account or a member account.

In a management account, you can see the AWS organizations permissions, the count of linked accounts, and the total number of source servers, applications, and waves under Account information. The Linked accounts section displays the relevant information for your linked accounts. It shows all the linked accounts this account has access to, including the account you’re logged into (the management account) and the member accounts that are linked to it. If the management account has access to two additional member accounts, the Linked accounts section will show three accounts. It’s the total number of accounts that are visible through this management account (including itself). For member accounts, this page only displays the account information that includes the AWS organizations permissions and the number of source servers, applications, and waves in the specific account.

Global view

In your management account, you can access and review source servers, applications and waves within your account and across all member accounts. As a manager, you can choose between All accounts and My account from the drop-down menu, which allows you to change you view of presented source servers, applications or waves.

Waves

Import and Export from Local Disk
A comprehensive data center inventory forms the foundation of any successful migration endeavor. This inventory encompasses a comprehensive list of servers and applications managed by customers on premises. The inventory is categorized into migration waves to facilitate efficient migration planning.

Typically, this inventory is compiled using discovery tools or created manually by IT administrators. Perhaps you maintain your data center inventory in Excel spreadsheets. With Application Migration Service, we offer seamless support for importing your inventory list from a CSV file, which follows a format similar to the one used by Cloud Migration Factory.

In the previous release, Application Migration Service supported the option to import a file from Amazon S3 and export a file to Amazon S3. In this latest release, Application Migration Service supports the option to import a file from local disk and export a file to local disk. This makes it easy for you to manage large scale-migrations and ingest your inventory of source servers, applications and waves, including their attributes such as EC2 instance type, subnet and tags. These attributes are the parameters used to populate the EC2 launch template.

Import and Export

To start using the import feature, you need to identify your servers and application inventory. You can do this manually or using discovery tools. The next thing you need to do is download the import template, which you can access from the console.

Import Local

After you download the import template, you can start mapping your inventory list onto this template. While mapping your inventory, you can group related servers into applications and waves. You can also perform configurations, such as defining Amazon Elastic Compute Cloud (Amazon EC2) launch template settings and specifying tags for each wave.

The following screenshot is an example of the results of my import template.

Inventory

On the Application Migration Service page in the AWS Management Console, select Import on the left-side navigation menu (under Import and Export). Under the Import inventory tab, select Import from local disk. Select Choose file and choose the local file containing your inventory list. Select Import, and the inventory file is imported into Application Migration Service. When the import process is complete, the details of the import results appear.

Now, you can view all your inventory inside the Source servers, Applications, and Waves pages on the Application Migration Service console.

To export your inventory to a local file, select Export on the left-side navigation menu of the Application Migration Service page. Under Export inventory tab, choose Export to local disk. Specify the name of the file to download under Destination filename. Choose Export, and the inventory file downloads to your local disk. Application Migration Service uses an S3 bucket within your account for the import and export operations, even when using local disk. You must have the required permissions to perform this action. You can modify the exported inventory file and reimport it to perform bulk configuration updates across your inventory. When the global view feature is activated upon reimport, configuration changes are applied also across accounts.

Export Local

Additional Post-launch Actions
Post-launch actions allow you to control and automate actions performed after your servers have been launched in AWS. You can use predefined or custom post-launch actions.
Application Migration Service now has four additional predefined post-launch actions to run in your Amazon EC2 instances on top of the existing predefined post-launch actions. These additional post-launch actions provide you with flexibility to maximize your migration experience.

Post Launch template

The new four additional predefined post-launch actions are as follows:

  • Configure Time Sync – You can use the Time Sync feature to set the time for your Linux instance using ATSS.
  • Validate disk space – You can use the disk space validation feature to obtain visibility into the disk space and to ensure that you have enough available disk space on your target server.
  • Verify HTTP(S) response – You can use the Verify HTTP(S) response feature to conduct HTTP(S) connectivity checks to a predefined list of URLs. The feature verifies the connectivity to the launched target instance.
  • Enable Amazon Inspector – The Enable Amazon Inspector feature allows you to run security scans on your Amazon EC2 resources, including the target instances launched by Application Migration Service. The Amazon Inspector service is enabled at the account level. This action uses the Enable, BatchGetAccountStatus, and CreateServiceLinkedRole APIs.

Now Available
The Global View, Import and Export Feature from Local, and Additional Post-launch Actions are available now, and you can start using them today in all Regions where AWS Application Migration Service is supported. Visit the Application Migration Service User Guide to dive deeper into these exciting features and you can refer to the Getting started with AWS Application Migration Service to kickstart your workload migration to AWS.

—Irshad

Microservices discovery using Amazon EC2 and HashiCorp Consul

Post Syndicated from Marine Haddad original https://aws.amazon.com/blogs/architecture/microservices-discovery-using-amazon-ec2-and-hashicorp-consul/

These days, large organizations typically have microservices environments that span across cloud platforms, on-premises data centers, and colocation facilities. The reasons for this vary but frequently include latency, local support structures, and historic architectural decisions. However, due to the complex nature of these environments, efficient mechanisms for service discovery and configuration management must be implemented to support operations at scale. This is an issue also faced by Nomura.

Nomura is a global financial services group with an integrated network spanning over 30 countries and regions. By connecting markets East & West, Nomura services the needs of individuals, institutions, corporates, and governments through its three business divisions: Retail, Investment Management, and Wholesale (Global Markets and Investment Banking). E-Trading Strategy Foreign Exchange sits within Global Markets, and focuses on all quantitative analysis and technical aspects of electronic FX flows. The team builds out a number of innovative solutions for clients, all of which are needed to operate in an ultra-low latency environment to be competitive. The focus is to build high-quality engineered platforms that can handle all aspects of Nomura’s growing 24 hours a day, 5-and-a-half days a week FX business.

In this blog post, we share the solution we developed for Nomura and how you can build a service discovery mechanism that uses a hierarchical rule-based algorithm. We use the flexibility of Amazon Elastic Compute Cloud (Amazon EC2) and third-party software, such as SpringBoot and Consul. The algorithm supports features such as service discovery by service name, Domain Name System (DNS) latency, and custom provided tags. This can activate customers with automated deployments, since services are able to auto-discover and connect with other services. Based on provided tags, customers can implement environment boundaries so that a service doesn’t connect to an unintended service. Finally, we built a failover mechanism, so that if a service becomes unavailable, an alternative service would be provided (based on given criteria).

After reading this post, you can use the provided assets in the open source repository to deploy the solution in their sandbox environment. The Terraform and Java code that accompanies this post can be amended as needed to suit individual requirements.

Overview of solution

The solution is composed of a microservices platform that is spread over two different data centers, and a Consul cluster per data center. We use two Amazon Virtual Private Clouds (VPCs) to model geographically distributed Consul “data centers”. These VPCs are then connected via an AWS Transit Gateway. By permitting communication across the different data centers, the Consul clusters can form a wide-area network (WAN) and have visibility of service instances deployed to either. The SpringBoot microservices use the Spring Cloud Consul plugin to connect to the Consul cluster. We have built a custom configuration provider that uses Amazon EC2 instance metadata service to retrieve the configuration. The configuration provider mechanism is highly extensible, so anyone can build their own configuration provider.

The major components of this solution are:

    • Sample microservices built using Java and SpringBoot, and deployed in Amazon EC2 with one microservice instance per EC2 instance
    • A Consul cluster per Region with one Consul agent per EC2 instance
    • A custom service discovery algorithm
Multi-VPC infrastructure architecture

Figure 1. Multi-VPC infrastructure architecture

A typical flow for a microservice would be to 1/ boot up, 2/ retrieve relevant information from the EC2 Metadata Service (such as tags), and, 3/ use it to register itself with Consul. Once a service is registered with Consul it can discover services to integrate with, and it can be discovered by other services.

An important component of this service discovery mechanism is a custom algorithm that performs service discovery based on the tags created when registering the service with Consul.

Service discovery flow

Figure 2. Service discovery flow

The service flow shown in Figure 2 is as follows:

  1. The Consul agent deployed on the instance registers to the local Consul cluster, and the service registers to its Consul agent.
  2. The Trading service looks up for available Pricer services via API calls.
  3. The Consul agent returns the list of available Pricer services, so that the Trading service can query a Pricer service.

Walkthrough

Following are the steps required to deploy this solution:

  • Provision the infrastructure using Terraform. The application .jar file and the Consul configuration are deployed as part of it.
  • Test the solution.
  • Clean up AWS resources.

The steps are detailed in the next section, and the code can be found in this GitHub repository.

Prerequisites

Deployment steps

Note: The default AWS Region used in this deployment is ap-southeast-1. If you’re working in a different AWS Region, make sure to update it.

Clone the repository

First, clone the repository that contains all the deployment assets:

git clone https://github.com/aws-samples/geographical-hierarchical-service-lookup-with-consul-on-aws

Build Amazon Machine Images (AMIs)

1. Build the Consul Server AMI in AWS

Go to the ~/deployment/scripts/amis/consul-server/ directory and build the AMI by running:

packer build .

The output should look like this:

==>  Builds finished. The artifacts of successful builds are:

-->  amazon-ebs.ubuntu20-ami: AMIs were created:

ap-southeast-1: ami-12345678910

Make a note of the AMI ID. This will be used as part of the Terraform deployment.

2. Build the Consul Client AMI in AWS

Go to ~/deployment/scripts/amis/consul-client/ directory and build the AMI by running:

packer build .

The output should look like this:

==> Builds finished. The artifacts of successful builds are:

--> amazon-ebs.ubuntu20-ami: AMIs were created:

ap-southeast-1: ami-12345678910

Make a note of the AMI ID. This will be used as part of the Terraform deployment.

Prepare the deployment

There are a few steps that must be accomplished before applying the Terraform configuration.

1. Update deployment variables

    • In a text editor, go to directory ~/deployment/
    • Edit the variable file template.var.tfvars.json by adding the variables values, including the AMI IDs previously built for the Consul Server and Client

Note: The key pair name should be entered without the “.pem” extension.

2. Place the application file .jar in the root folder ~/deployment/

Deploy the solution

To deploy the solution, run the following commands from the terminal:

export  VAR_FILE=template.var.tfvars.json

terraform init && terraform plan --var-file=$VAR_FILE -out plan.out

terraform apply plan.out

Validate the deployment

All the EC2 instances have been deployed with AWS Systems Manager access, so you can connect privately to the terminal using the AWS Systems Manager Session Manager feature.

To connect to an instance:

1. Select an instance

2. Click Connect

3. Go to Session Manager tab

Using Session Manager, connect to one of the Consul servers and run the following commands:

consul members

This command shows you the list of all Consul servers and clients connected to this cluster.

consul members -wan

This command shows you the list of all Consul servers connected to this WAN environment.

To see the Consul User Interface:

1. Open your terminal and run:

aws ssm start-session --target <instanceID> --document-name AWS-StartPortForwardingSession --parameters '{"portNumber":["8500"],"localPortNumber":["8500"]}' --region <region>

Where instanceID is the AWS Instance ID of one of the Consul servers, and Region is the AWS Region.

Using System Manager Port Forwarding allows you to connect privately to the instance via a browser.

2. Open a browser and go to http://localhost:8500/ui

3. Find the Management Token ID in AWS Secrets Manager in the AWS Management Console

4. Login to the Consul UI using the Management Token ID

Test the solution

Connect to the trading instance and query the different services:

curl http://localhost:9090/v1/discover/service/pricer

curl http://localhost:9090/v1/discover/service/static-data

This deployment assumes that the Trading service queries the Pricer and Static-Data services, and that services are returned based on an order of precedence (see Table 1 following):

Service Precedence Customer Cluster Location Environment
TRADING 1 ACME ALPHA DC1 DEV
PRICER 1 ACME ALPHA DC1 DEV
PRICER 2 ACME ALPHA DC2 DEV
PRICER 3 ACME BETA DC1 DEV
PRICER 4 ACME BETA DC2 DEV
PRICER 5 SHARED ALPHA DC1 DEV
PRICER 6 SHARED ALPHA DC2 DEV
STATIC-DATA 1 SHARED SHARED DC1 DEV
STATIC-DATA 2 SHARED SHARED DC2 DEV
STATIC-DATA 2 SHARED BETA DC2 DEV
STATIC-DATA 2 SHARED GAMMA DC2 DEV
STATIC-DATA -1 STARK ALPHA DC1 DEV
STATIC-DATA -1 ACME BETA DC2 PROD

Table 1. Service order of precedence

To test the solution, switch on and off services in the AWS Management Console and repeat Trading queries to look at where the traffic is being redirected.

Cleaning up

To avoid incurring future charges, delete the solution from ~/deployment/ in the terminal:

terraform destroy --var-file=$VAR_FILE

Conclusion

In this post, we outlined the prevalent challenge of complex globally distributed microservice architectures. We demonstrated how customers can build a hierarchical service discovery mechanism to support such an environment using a combination of Amazon EC2 service and third-party software such as SpringBoot and Consul. Use this to test this solution into your sandbox environment and to see if it could bring the answer to your current challenge.

Additional resources:

Deploying low-latency hybrid cloud storage on AWS Local Zones using AWS Storage Gateway

Post Syndicated from maceneff original https://aws.amazon.com/blogs/compute/deploying-low-latency-hybrid-cloud-storage-on-aws-local-zones-using-aws-storage-gateway/

This blog post is written by Ruchi Nigam, Senior Cloud Support Engineer and Sumit Menaria, Senior Hybrid SA.

AWS Local Zones are a type of infrastructure deployment that places compute, storage, database, and other select AWS services close to large population and industry centers. With Local Zones close to large population centers in metro areas, customers can achieve the low latency required for use cases like video analytics, online gaming, virtual workstations, live streaming, remote healthcare, and augmented and virtual reality. They can also help customers operating in regulated sectors like healthcare, financial services, mining and resources, and public sector that might have preferences or requirements to keep data within a geographic boundary. In addition to low-latency and residency benefits, Local Zones can help organizations migrate additional workloads to AWS, supporting a hybrid cloud migration strategy and simplifying IT operations.

Your hybrid cloud migration strategy may involve storage requirements for data coming in from various on-premises sources, file sharing within the organization or backup on-premises files. These storage requirements can be met by using Amazon FSx for a feature-rich, high performance file system. You can deploy your workload in the nearest Local Zones and use Amazon FSx in the parent AWS Region for a cost-effective solution with four widely-used file systems: NetApp ONTAP, OpenZFS, Windows File Server, and Lustre.

If your workloads need low-latency access to your storage solution and operate in locations which are not close to an AWS Region, then you can consider AWS Storage Gateway as a set of hybrid cloud storage services to get access to virtually unlimited cloud storage in the region. There are options to deploy Storage Gateway directly in your on-premises environment as a virtual machine (VM) (VMware ESXi, Microsoft Hyper-V, Linux KVM) or as a pre-configured standalone hardware appliance. But you can also deploy it on an Amazon Elastic Compute Cloud (Amazon EC2) instance in Local Zones or the Region, depending where your data sources and users are. Deploying Storage Gateway on Amazon EC2 in Local Zones provides low latency access via local cache for your applications while taking away the undifferentiated heavy lifting of management of the power, space, and hardware for deploying it in the on-premises environment. Before choosing an appropriate location, you must note any data residency requirements with which you must comply. There may be situations where the Local Zone’s parent Region is in the same country. However, it is recommended to work with your compliance and security teams for confirmation, as the objects are stored in the Amazon S3 service in the Region.

Depending on your use cases you can choose among four different deployment options: Amazon S3 File Gateway, Amazon FSx File Gateway , Tape Gateway, and Volume Gateway.

Name

Interface

Use Case

S3 File Gateway

NFS, SMB

Allow on-premises or EC2 instances to store files as objects in Amazon S3 and access them via NFS or SMB mount points

Volume Gateway Stored Mode

iSCSI

Asynchronous replication of on-premises data to Amazon S3

Volume Gateway Cached Mode

iSCSI

Primary data stored in Amazon S3 with frequently accessed data cached locally on-premises

Tape Gateway

ISCSI

Replace on-premises physical tapes with AWS-backed virtual tapes. Provides virtual media changer and tape drives to use with existing backup applications

FSx File Gateway

SMB

Low-latency, efficient connection for remote users when moving on-premises Windows file systems into the cloud.

We expand on how you can deploy Amazon S3 File Gateway in a Local Zones specific setup. However, a similar approach can be used for other deployment options.

Amazon S3 File Gateway on Local Zones

Amazon S3 File Gateway provides a seamless way to connect to the cloud to store application data files and backup images as durable objects in Amazon S3 cloud storage. Amazon S3 File Gateway supports a file interface into Amazon S3 and combines a service and a virtual software appliance. The gateway offers Server Message Block (SMB) or Network File System (NFS)-based access to data in Amazon S3 with local caching. This can be used for both on-premises and data-intensive Amazon EC2-based applications in Local Zones that require file protocol access to Amazon S3 object storage.

Architecture

Amazon S3 File Gateway on Local Zones architecture setup

In the previous architecture, Client connects to the Storage Gateway EC2 instance over a private/public connection. Storage Gateway EC2 instance can access the S3 bucket in the Region via the Storage Gateway service endpoint. The File Share associated with the Storage Gateway presents the S3 bucket as a locally mounted drive for the client to use.

There are few things we must note while deploying file gateway on Amazon EC2 in a Local Zone.

  • Since there are selected EC2 instance types available in the Local Zones, identify the instance types available in your desired Local Zone and select the appropriate one which meets the file gateway requirements from a memory perspective.

For example, to list the EC2 instance types offered in the ‘us-east-1-bos-la’ Availability Zone (AZ), use the following command:

aws ec2 describe-instance-type-offerings —location-type
"availability-zone" —filters Name=location,Values=us-east-1-bos-
1a —region us-east-1
  • Choose a supported instance type and EBS volumes in the Local Zone.
  • Add another 150GiB storage apart from the root volume for cache storage.
  • Review and make sure that the Security Group has correct firewall ports open – SMB/NFS ports, HTTP port (for activation) are open in ingress.
  • For activation, if you must access the Storage Gateway over the Public network, then you must assign a Public IP address to the EC2 instance. If you plan to use an Elastic IP address, then make sure that you select the network-border group specific to the Local Zone.
  • For private connectivity, you can use an AWS Direct Connect connection at the supported Local Zones and also enable VPC endpoint for connectivity between Storage Gateway and service endpoints.

Setting up Amazon S3 File Gateway

1.      Navigate to the Storage Gateway console and select the Create Gateway button. In the Gateway options, select the Gateway type as Amazon S3 File Gateway.

Step-1 Select the Gateway type

2.      Under Platform options, select Amazon EC2 and select the option to Customize your settings.

Step-2 Platform options and customize settings

Then, select the Launch instance button and complete launching the EC2 instance to be used as the Storage Gateway. Navigating to the launch instance wizard picks up the verified file gateway Amazon Machine Image (AMI) available in the Region. However, you can also find the AMI using the following AWS Command Line Interface (AWS CLI) command:

aws --region us-east-1 ssm get-parameter --name
/aws/service/storagegateway/ami/FILE_S3/latest

3.      After launching the EC2 instance, check Confirm set up gateway and select Next.

Step-3 Confirm set up gateway

4.      Under Gateway connection options, choose the IP address radio button and enter the Public IP of the EC2 instance launched in Step 2.

Step-4 Gateway connection options

5.      For the Storage Gateway Service endpoint connection, you can create a VPC endpoint for Storage Gateway and specify the VPC endpoint ID from the dropdown selections for a private connection between the gateway and AWS Storage Services. Alternatively, you can choose the Publicly accessible option.

Step-5 Service endpoint connection options

6.      Review and activate the storage gateway.

Step-6 Review and activate

7.      Once the gateway is activated, you can allocate cache storage from the local disks. It is recommended to only use Amazon Elastic Block Store (Amazon EBS) volumes for the gateway storage.

Step-7 Configure cache storage

Once the gateway is configured, the next steps show how to create a file share that can be accessed using the NFS or the SMB protocol.

8.      A File Gateway can host multiple NFS and SMB file shares. For this example, we configure the NFS file share type. You can also select the corresponding S3 bucket in the Region which is going to be used for storing the data.

Step 7 - Create file share

Once the file share is created, you can see the list of mount commands to be used on different clients.

Example mount commands for different clients

On a Linux Client, use the following steps to mount the previously created NFS file share. Make sure you replace the IP address, S3 bucket name, and mount path with names specific to your configuration.

sudo mount -t nfs -o nolock,hard 10.0.32.151:/my-s3-bucket /my-
mount-path

You can verify that the file share has been mounted by running the following command:

$ df -TH
Filesystem Type Size Used Avail Use% Mounted on
devtmpfs devtmpfs 497M 0 497M 0% /dev
tmpfs tmpfs 506M 476k 506M 1% /run
tmpfs tmpfs 506M 0 506M 0% /sys/fs/cgroup
/dev/xvda1 xfs 8.6G 7.3G 1.4G 85% /
10.0.32.151:/my-s3-bucket nfs4 9.3E 0 9.3E 0% /your-mount-path
tmpfs tmpfs 102M 0 102M 0% /run/user/0
tmpfs tmpfs 102M 0 102M 0% /run/user/1000

Now you can also list the S3 objects as files on the locally mounted drive.

Terminal output listing files on Storage Gateway

For reference, here are the objects stored in the S3 bucket in the Region.

Objects stored in S3 bucket in the Region

To see a recently added object in the S3 bucket, select Refresh cache under the Actions options of the file share.

Depending on the client location, performance for access to the cached files is better as compared to direct access to the files in the parent Region. The clients can be either in your on-premises and accessed via Direct Connect to the Local Zone, or workload within the Local Zone, which can mount the file gateway for local access from the VPC.

Furthermore, you can look at Amazon S3 File Gateway performance for clients to select the appropriate EC2 instance type and EBS volume size and monitor Cache hit, Read/Write Time, and other performance metrics of the storage gateway by using CloudWatch Metrics.

Cleaning Up

  1. Unmount the File Gateway from the local machine: unmount /your-mount-path
  2. Delete the Storage Gateway from the Storage Gateway console
  3. Delete the VPC Endpoint created for Storage Gateway service
  4. Delete the EC2 instance from the Amazon EC2 console
  5. Delete the files added to the S3 bucket from the Amazon S3 console

Conclusion

By deploying Amazon Storage Gateway on Local Zones, you can utilize the scalability, security, and cost-effectiveness of the AWS cloud, and simultaneously provide low-latency and high-performance access for on-premises applications and users. This can accelerate the migration your storage workloads to cloud while providing your users with low latency access via Local Zones in a truly hybrid manner. Read more about AWS Storage Gateway and AWS Local Zones in their respective documentation.

New – Amazon EC2 Hpc7g Instances Powered by AWS Graviton3E Processors Optimized for High Performance Computing Workloads

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-amazon-ec2-hpc7g-instances-powered-by-aws-graviton3e-processors-optimized-for-high-performance-computing-workloads/

At AWS re:Invent 2022, Adam Selipsky, CEO of AWS, explained high performance computing (HPC) workloads typically can either be compute-intensive, compute- and networking-intensive, or data- and memory-intensive in his keynote.

Compute workloads include weather forecasting, computational fluid dynamics, and financial options pricing. To help with this, you have Amazon EC2 Hpc6a instances, which deliver up to 65 percent better price performance over comparable compute optimized x86-based instances.

Other HPC workloads require modeling the performance of complex structures—things like wind turbines, concrete buildings, and industrial equipment. Without enough data and memory, these models can take days or weeks to run in a cost-effective way. The Amazon EC2 Hpc6id instance is designed to deliver leading price performance for data and memory-intensive HPC workloads with higher memory bandwidth per core, faster local solid-state drive (SSD) storage, and enhanced networking with Elastic Fabric Adapter (EFA).

Announcing Amazon EC2 Hpc7g Instances
Compute-intensive HPC workloads such as weather forecasting, computational fluid dynamics, and financial options pricing also require more network performance, even better price performance, and greater energy efficiency.

Today we are announcing the general availability of Amazon EC2 Hpc7g instances, a new purpose-built instance type for tightly coupled compute and network-intensive HPC workloads.

Hpc7g instances are powered by AWS Graviton3E processors that provide up to two times better floating-point performance and 200 Gbps dedicated EFA bandwidth than EC2 C6gn instances powered by AWS Graviton2 processors and are up to 60 percent more energy efficient than comparable x86 instances.

Here’s a quick infographic that shows you how the Hpc7g instances and the Graviton3E processors compare to previous instances and processors:

Hpc7g instances feature sizes of up to 64 cores of the latest AWS custom Graviton3E CPUs with 128 GiB RAM. Here are the detailed specs:

Instance Name
CPUs RAM (GiB)
EFA Network Bandwidth (Gbps) Attached Storage
hpc7g.4xlarge 16 128 Up to 200 EBS Only
hpc7g.8xlarge 32 128 Up to 200 EBS Only
hpc7g.16xlarge 64 128 Up to 200 EBS Only

Hpc7g instances are the most cost-efficient option to scale your HPC clusters on AWS. If you are considering migrating your largest HPC workloads requiring tens of thousands of cores at scale to AWS, you can take advantage of up to 200 Gbps EFA bandwidth to reduce the latency and run message passing interface (MPI) applications on parallel computing architectures while ensuring minimized power consumption on Hpc7g instances.

You can choose to use smaller sizes of Hpc7g instances to pick a lower number of cores and evenly distribute memory and network resources across the remaining cores to increase per-core performance to help reduce software licensing costs.

You can also use Hpc7g instances with AWS ParallelCluster to offer a complete HPC run-time environment that spans both x86 and arm64 instance types, giving you the flexibility to run different workload types within the same HPC cluster. You can compare and contrast performance, thus making it easier to find out what’s best for you and enabling easier porting of your workload.

Customer Story
The Water Institute is an independent, non-profit applied research organization that works across disciplines to advance science and develop integrated methods used to solve complex environmental and societal challenges.

They benchmarked the Hpc7g instances with 200 Gbps EFA using the Advanced Circulation (ADCIRC) model. ADCIRC is deployed throughout many US government agencies to simulate the movement of water due to astronomic tides, riverine flows, and atmospheric forces, including hurricanes and it is often used for real-time forecasting applications and design studies.

The model run for this application is targeted at Southern Louisiana and is the basis for most of the analysis conducted there including levee design, planning studies, and real-time hurricane storm surge forecasting applications. The left graphic above shows the full extent of the domain, while to the right of that, the high-resolution area targeted at Southern Louisiana shows flooding around the levees in New Orleans during a simulation of Hurricane Katrina.

The model contains 1.6 million vertices and 3 million elements. It’s these parameters that affect the computational complexity of the simulations. The simulations depict 18 days of astronomic tide, river inflows, and atmospheric wind and pressure forcing.

The Water Institute benchmarked against many of the instance types that would be useful for their workload types at AWS, including c6gn.16xlarge, hpc7g.16xlarge, hpc6a.48xlarge, and hpc6id.36xlarge.

The Hpc7g instance shows more than 40 percent better performance than the C6gn instance and has comparable performance to other high performance x86 instance types but with a better price-to-performance ratio. With Hpc7g instances, the Water Institute can lower its costs while maintaining the performance levels they expect.

RIKEN, who has built the powerful supercomputer, FUGAKU using arm64, is collaborating with AWS to create a virtual Fugaku using Hpc7g with Graviton3E to support Japanese manufacturers’ increasing demand for compute power. RIKEN has already confirmed that multiple Fugaku applications provide excellent performance on the AWS Graviton3E processor in the AWS cloud environment.

Also, Siemens has optimized the scalability of Simcenter STAR-CCM+ across a broad range of CPU and GPU instances on AWS. This technology is supported on Linux and available through Arm-based EC2 instances or the Fugaku supercomputer.

To hear more voices of customers and partners such as Ansys, Arup, CERFACS, ESI, Jij, ParTec, Rescale, and TotalCAE, see the Hpc7g instances page.

Now Available
Amazon EC2 Hpc7g instances are now generally available in the US East (N. Virginia) Region for purchase in On-Demand, Reserved Instance, and Savings Plan form.

To learn more, see the Amazon EC2 Hpc7g instances page. Give it a try, and please send feedback to AWS re:Post for High Performance Compute or through your usual AWS support contacts.

– Channy

New Amazon EC2 C7gn Instances: Graviton3E Processors and Up To 200 Gbps Network Bandwidth

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-amazon-ec2-c7gn-instances-graviton3e-processors-and-up-to-200-gbps-network-bandwidth/

The C7gn instances that we previewed last year are now available and you can start using them today. The instances are designed for your most demanding network-intensive workloads (firewalls, virtual routers, load balancers, and so forth), data analytics, and tightly-coupled cluster computing jobs. They are powered by AWS Graviton3E processors and support up to 200 Gbps of network bandwidth.

Here are the specs:

Instance Name vCPUs
Memory
Network Bandwidth
EBS Bandwidth
c7gn.medium 1 2 GiB up to 25 Gbps up to 10 Gbps
c7gn.large 2 4 GiB up to 30 Gbps up to 10 Gbps
c7gn.xlarge 4 8 GiB up to 40 Gbps up to 10 Gbps
c7gn.2xlarge 8 16 GiB up to 50 Gbps up to 10 Gbps
c7gn.4xlarge 16 32 GiB 50 Gbps up to 10 Gbps
c7gn.8xlarge 32 64 GiB 100 Gbps up to 20 Gbps
c7gn.12xlarge 48 96 GiB 150 Gbps up to 30 Gbps
c7gn.16xlarge 64 128 GiB 200 Gbps up to 40 Gbps

The increased network bandwidth is made possible by the new 5th generation AWS Nitro Card. As another benefit, these instances deliver the lowest Elastic Fabric Adapter (EFA) latency of any current EC2 instance.

Here’s a quick infographic that shows you how the C7gn instances and the Graviton3E processors compare to previous instances and processors:

As you can see, the Graviton3E processors deliver substantially higher memory bandwidth and compute performance than the Graviton2 processors, along with higher vector instruction performance than the Graviton3 processors.

C7gn instances are available in the US East (Ohio, N. Virginia), US West (Oregon), and Europe (Ireland) AWS Regions in On-Demand, Reserved Instance, Spot, and Savings Plan form. Dedicated Instances and Dedicated Hosts are also available.

— Jeff;

AWS Week in Review – Amazon EC2 Instance Connect Endpoint, Detective, Amazon S3 Dual Layer Encryption, Amazon Verified Permission – June 19, 2023

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-week-in-review-amazon-ec2-instance-connect-endpoint-detective-amazon-s3-dual-layer-encryption-amazon-verified-permission-june-19-2023/

This week, I’ll meet you at AWS partner’s Jamf Nation Live in Amsterdam where we’re showing how to use Amazon EC2 Mac to deploy your remote developer workstations or configure your iOS CI/CD pipelines in the cloud.Mac in an instant

Last Week’s Launches
While I was traveling last week, I kept an eye on the AWS News. Here are some launches that got my attention.

Amazon EC2 Instance Connect Endpoint. Endpoint for EC2 Instance Connect allows you to securely access Amazon EC2 instances using their private IP addresses, making the use of bastion hosts obsolete. Endpoint for EC2 Instance Connect is by far my favorite launch from last week. With EC2 Instance Connect, you use AWS Identity and Access Management (IAM) policies and principals to control SSH access to your instances. This removes the need to share and manage SSH keys. We also updated the AWS Command Line Interface (AWS CLI) to allow you to easily connect or open a secured tunnel to an instance using only its instance ID. I read and contributed to a couple of threads on social media where you pointed out that AWS Systems Manager Session Manager already offered similar capabilities. You’re right. But the extra advantage of EC2 Instance Connect Endpoint is that it allows you to use your existing SSH-based tools and libraries, such as the scp command.

Amazon Inspector now supports code scanning of AWS Lambda functions. This expands the existing capability to scan Lambda functions and associated layers for software vulnerabilities in application package dependencies. Amazon Detective also extends finding groups to Amazon Inspector. Detective automatically collects findings from Amazon Inspector, GuardDuty, and other AWS security services, such as AWS Security Hub, to help increase situational awareness of related security events.

Amazon Verified Permissions is generally available. If you’re designing or developing business applications that need to enforce user-based permissions, you have a new option to centrally manage application permissions. Verified Permissions is a fine-grained permissions management and authorization service for your applications that can be used at any scale. Verified Permissions centralizes permissions in a policy store and helps developers use those permissions to authorize user actions within their applications. Similarly to the way an identity provider simplifies authentication, a policy store lets you manage authorization in a consistent and scalable way. Read Danilo’s post to discover the details.

Amazon S3 Dual-Layer Server-Side Encryption with keys stored in AWS Key Management Service (DSSE-KMS). Some heavily regulated industries require double encryption to store some type of data at rest. Amazon Simple Storage Service (Amazon S3) offers DSSE-KMS, a new free encryption option that provides two layers of data encryption, using different keys and different implementation of the 256-bit Advanced Encryption Standard with Galois Counter Mode (AES-GCM) algorithm. My colleague Irshad’s post has all the details.

AWS CloudTrail Lake Dashboards provide out-of-the-box visibility and top insights from your audit and security data directly within the CloudTrail Lake console. CloudTrail Lake features a number of AWS curated dashboards so you can get started right away – with no required detailed dashboard setup or SQL experience.

AWS IAM Identity Center now supports automated user provisioning from Google Workspace. You can now connect your Google Workspace to AWS IAM Identity Center (successor to AWS Single Sign-On) once and manage access to AWS accounts and applications centrally in IAM Identity Center.

AWS CloudShell is now available in 12 additional regions. AWS CloudShell is a browser-based shell that makes it easier to securely manage, explore, and interact with your AWS resources. The list of the 12 new Regions is detailed in the launch announcement.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Here are some other updates and news that you might have missed:

  • AWS Extension for Stable Diffusion WebUI. WebUI is a popular open-source web interface that allows you to easily interact with Stable Diffusion generative AI. We built this extension to help you to migrate existing workloads (such as inference, train, and ckpt merge) from your local or standalone servers to the AWS Cloud.
  • GoDaddy developed a multi-Region, event-driven system. Their system handles 400 millions events per day. They plan to scale it to process 2 billion messages per day in a near future. My colleague Marcia explains the detail of their architecture in her post.
  • The Official AWS Podcast – Listen each week for updates on the latest AWS news and deep dives into exciting use cases. There are also official AWS podcasts in several languages. Check out the podcasts in French, German, Italian, and Spanish.
  • AWS Open Source News and Updates – This is a newsletter curated by my colleague Ricardo to bring you the latest open source projects, posts, events, and more.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

  • AWS Silicon Innovation Day (June 21) – A one-day virtual event that will allow you to better understand AWS Silicon and how you can use the Amazon EC2 chip offerings to your benefit. My colleague Irshad shared the details in this post. Register today.
  • AWS Global Summits – There are many AWS Summits going on right now around the world: Milano (June 22), Hong Kong (July 20), New York (July 26), Taiwan (Aug 2 & 3), and Sao Paulo (Aug 3).
  • AWS Community Day – Join a community-led conference run by AWS user group leaders in your region: Manila (June 29–30), Chile (July 1), and Munich (September 14).
  • AWS User Group Perú Conf 2023 (September 2023). Some of the AWS News blog writer team will be present: Marcia, Jeff, myself, and our colleague Startup Developer Advocate Mark. Save the date and register today.
  • CDK Day – CDK Day is happening again this year on September 29. The call for papers for this event is open, and this year we’re also accepting talks in Spanish. Submit your talk here.

That’s all for this week. Check back next Monday for another Week in Review!

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!
— seb

Deploying an automated Amazon CloudWatch dashboard for AWS Outposts using AWS CDK

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/deploying-an-automated-amazon-cloudwatch-dashboard-for-aws-outposts-using-aws-cdk/

This post is written by Enrico Liguori, Networking Solutions Architect, Hybrid Cloud and Sumeeth Siriyur, Sr. Hybrid Cloud Solutions Architect.

AWS Outposts is a fully managed service that brings the same AWS infrastructure, services, APIs, and tools to virtually any data center, colocation space, manufacturing floor, or on-premises facility where it might be needed. With Outposts, you can run some AWS services on-premises and connect to a broad range of services available in the local AWS Region. Outposts supports workloads requiring low latency, local data processing, data residency, and application migration.

Outposts capacity is driven as per your compute and storage requirements to run workloads. You can monitor Outposts resources using metrics gathered by Amazon CloudWatch. Using these metrics, you can effectively monitor and manage the Outposts resources as they would in the Region, levereging cloud native tools such as CloudWatch dashboards. Check the Monitoring best practices for AWS Outposts blog post to dive deep into the available monitoring options for Outposts.

CloudWatch dashboards are customizable home pages in the CloudWatch console that can be used to monitor resources running on Outposts in a single view. For example, you can monitor in a single pane the number Amazon EC2 instances used per EC2 instance type, the available capacity of Amazon EBS volumes and Amazon S3 buckets, and the operational status of the service link of Outposts.

As a you start deploying additional Outposts resources as a part of their capacity expansion, they must all be integrated and visualized within CloudWatch in an automated way. Traditionally CloudWatch dashboards are built manually and may be time consuming to tune. This post provides also an overview of building CloudWatch dashboards in an automated way using AWS Cloud Development Kit (AWS CDK).

Overview

CloudWatch metrics available to monitor Outposts resources and capacity

CloudWatch metrics for Outposts are available to customers in all public AWS Regions and AWS GovCloud (US) at no additional cost. We can classify the available metrics in two main categories:

To identify the metrics published under the service specific namespaces, we can leverage metadata in the form of tags. A tag is a label that you assign to an AWS resource and consists of a key and an optional value. For the purpose of the monitoring strategy described in this post, we use a tag that contains the OutpostID of the Outpost where the resource is deployed. In this way, we can easily filter the CloudWatch metrics that we would like to show in our dashboard.

To enforce the assignment of tags to our resources we can implement a tagging strategy using AWS tag Policies and Service Control Policies (SCPs).

The following sections describe two different methods to build a CloudWatch dashboard that includes the different types of metrics described so far. In both cases, we see how particularly useful the presence of tags is to identify the service-specific metrics.

Manual approach to building a CloudWatch dashboard for Outposts

This section describes a manual (i.e., non-automated) approach to building a dashboard that could summarize both the capacity utilization metrics and the service specific metrics for your resources running on Outposts.

The benefit of this approach is that we can implement a fully operational dashboard directly from the CloudWatch console. However, it will simultaneously require more effort to properly tune the dashboard to satisfy your monitoring requirements.

You can start creating the dashboard opening the CloudWatch console and following the steps listed in the public documentation.

To display a metric under AWS/Outposts namespace we can choose any of the widgets available. Based on the nature of the data, we can choose different types of Widgets such as Number, Line, Gauge, Explorer, or you can even build your own custom widget.

Together with the Widget type, we must select Outposts namespace in the metric graph dialog box and then navigate to the specific metric of interest.

In case we are creating the dashboard in a different account than the Outposts owner, we must select the right account in the View data drop-down menu to see the Outposts metric in which we are interested.

View data drop-down menu

After selecting one or more metrics we can select Create widget button.

For the service specific metrics, we recommend using the explorer widget. In this way, we can utilize the tagging strategy described earlier to automatically identify the metrics belonging to the resources running on Outposts. Check the documentation page for a step-by-step guide for creating an explorer widget based on tags.

Automated outpost dashboard

After we’ve seen how to build a dashboard manually from the console, in this secton we describe an automated approach to deploy a dashboard for Outposts through AWS CDK.

AWS CDK is an open source software development framework to model and provision your cloud application resources using familiar programming languages, including TypeScript, JavaScript, Python, C#, and Java. For the solution in this post, we use Python.

Architecture overview

The AWS CDK stack described in this post, assumes that the resources running on Outposts (EC2 instances, S3 buckets, Application Load Balancers (ALBs), and RDS instances) are tagged using the tagging strategy described earlier.

Specifying a tag name and a tag value in a configuration file automatically discovers the resources with that tag and adds the related metrics to the CloudWatch dashboard.

Together with the service specific metrics, it creates a series of widgets that we can use to monitor the capacity available and utilized in each Outpost that belongs to the account where the script is running.

The workflow is made of the following phases:

  1. The AWS CDK stack creates an AWS CodeCommit repository and uploads its own code into it. The code contains a series of modules, one for each section of the CloudWatch dashboard. A section of the dashboard contains one or more widgets showing the metrics of a specific service.
  2. To maintain the CloudWatch dashboard always up-to-date with the resources matching the tag, it creates a pipeline in AWS CodePipeline that can dynamically create and or update the dashboard. The pipeline runs the code in the CodeCommit repository and is made of two stages. In the first one, the build stage, it builds the dependencies needed by the AWS CDK stack. In the second stage, the Deploy stage, it loads and runs the modules used to build the dashboard.
  3. Each module contains the code to automatically discover the tagged resources of a specific service. This discovery phase uses standard AWS APIs called through the Python SDK Boto3.
  4. Based on the results of the discovery phase, AWS CDK produces an AWS CloudFormation template containing the definition of the CloudWatch dashboard sections. The template is submitted to CloudFormation.
  5. CloudFormation creates or, if already defined, updates the CloudWatch dashboard.
  6. Together with the dashboard, the AWS CDK script also contains the definition of a CloudWatch Event that, once deployed, triggers the pipeline each time a resource tagged with the specified tag is created or destroyed.

Prerequisites

To implement the solution presented in this post, you must configure:

  1. git as distributed version control system.
  2. In case it is the first time that you’re using AWS CDK in this account and region, you must:

a. Install the AWS CDK, and its prerequisites, following these instructions.

b. Go through the AWS CDK bootstrapping process. This is required only for the first time that we use AWS CDK in a specific AWS environment (an AWS environment is a combination of an AWS account and Region).

How to install

Step 1: Clone the AWS CDK code hosted on GitHub with:

$ git clone https://github.com/aws-samples/automated-cloudwatch-dashboard.git

Step 2: enter the directory using the following:

$ cd  automated-cloudwatch-dashboard/

Step 3: Install the needed Python dependencies with:

$ pip install -r requirements.txt

Step 4: Modify the configuration file

Before deploying the stack, we must modify the configuration file to specify the tag we use for identifying our resources running on Outposts. Open the file with the name config.yaml with your preferred text editor and specify:

      • A name for the dashboard. The default name used is Automated-CloudWatch-Dashboard.
      • Replace <tag_name> placeholder following the tag_name variable with the tag name used to tag the resources that you want to include in the dashboard.
      • Replace <tag_value> placeholder under tag_values variable with the tag value that you used.

Here is an example config.yaml configuration file:

dashboard_name: Automated-CloudWatch-Dahsboard
tag_name: OutpostID
tag_values:
  - op-1234567890abcdefg 

Stack deployment

We can deploy the stack with the following:

$ cdk deploy

At the end of the deployment process, the pipeline that creates the dashboard is provisioned. You can now go to your CloudWatch console to view it.

Automated Outposts dashboard overview

Now that we have built our dashboard, let’s review each section:

  1. Outpost capacity

Outpost Capacity diagram

The AWS CDK stacks define a capacity section for each Outpost available to the AWS account where the script runs.

In this section, we find four widgets showing metrics published under the AWS/Outpost namespace. The first widget shows for each EC2 instance type available on the Outposts the number of instances utilized and available for that instance type. In the second row, we can visualize the available capacity for the Amazon EBS volumes and for the S3 buckets. The last widget shows the operational status of the service link of Outposts.

2. EC2 instances

CPU, Network, and Disk Utilization for an EC2 instance diagram

In this section of the dashboard, we find the metrics showing the CPU, Network, and Disk Utilization for an EC2 instance. It has defined a section of this type for each EC2 instance with a tag assigned matching the name and the value specified in the configuration file of the script.

3. Application Load Balancer

The ALB section aggregates metrics showing the operational status of a load balancer hosted on Outposts

The ALB section aggregates metrics showing the operational status of a load balancer hosted on Outposts. A section of this type is defined for each ALB with an assigned tag matching the one specified in the configuration file.

4. S3 buckets

The S3 buckets section diagram

The S3 buckets section is defined only once and aggregates the utilization metrics for all S3 buckets with an assigned tag.

5. AutoScaling group

The AutoScaling group section diagram

The AutoScaling group section can be used to monitor the number of instances in service in a specific AS group with a tag assigned. This section is defined once and can aggregate the metrics for multiple AutoScaling groups.

Clean up

To terminate the resources that we created in this post, run the following:

$ cdk destroy

Then, go to the Cloudformation console and delete the stack with the name “Deploy-AutomatedCloudWatchDashboard”.

Conclusion

In conclusion, this post demonstrates a manual way of creating CloudWatch Metrics dashboard using the CloudWatch console and an automated way using AWS CDK. The automated approach is also scalable by automatically discovering any new resources added to the existing Outposts in the your environment without any changes to the code.

Secure Connectivity from Public to Private: Introducing EC2 Instance Connect Endpoint

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/secure-connectivity-from-public-to-private-introducing-ec2-instance-connect-endpoint-june-13-2023/

This blog post is written by Ariana Rahgozar, Solutions Architect, and Kenneth Kitts, Sr. Technical Account Manager, AWS.

Imagine trying to connect to an Amazon Elastic Compute Cloud (Amazon EC2) instance within your Amazon Virtual Private Cloud (Amazon VPC) over the Internet. Typically, you’d first have to connect to a bastion host with a public IP address that your administrator set up over an Internet Gateway (IGW) in your VPC, and then use port forwarding to reach your destination.

Today we launched Amazon EC2 Instance Connect (EIC) Endpoint, a new feature that allows you to connect securely to your instances and other VPC resources from the Internet. With EIC Endpoint, you no longer need an IGW in your VPC, a public IP address on your resource, a bastion host, or any agent to connect to your resources. EIC Endpoint combines identity-based and network-based access controls, providing the isolation, control, and logging needed to meet your organization’s security requirements. As a bonus, your organization administrator is also relieved of the operational overhead of maintaining and patching bastion hosts for connectivity. EIC Endpoint works with the AWS Management Console and AWS Command Line Interface (AWS CLI). Furthermore, it gives you the flexibility to continue using your favorite tools, such as PuTTY and OpenSSH.

In this post, we provide an overview of how the EIC Endpoint works and its security controls, guide you through your first EIC Endpoint creation, and demonstrate how to SSH to an instance from the Internet over the EIC Endpoint.

EIC Endpoint product overview

EIC Endpoint is an identity-aware TCP proxy. It has two modes: first, AWS CLI client is used to create a secure, WebSocket tunnel from your workstation to the endpoint with your AWS Identity and Access Management (IAM) credentials. Once you’ve established a tunnel, you point your preferred client at your loopback address (127.0.0.1 or localhost) and connect as usual. Second, when not using the AWS CLI, the Console gives you secure and seamless access to resources inside your VPC. Authentication and authorization is evaluated before traffic reaches the VPC. The following figure shows an illustration of a user connecting via an EIC Endpoint:

Figure 1 shows a user connecting to private EC2 instances within a VPC through an EIC Endpoint

Figure 1. User connecting to private EC2 instances through an EIC Endpoint

EIC Endpoints provide a high degree of flexibility. First, they don’t require your VPC to have direct Internet connectivity using an IGW or NAT Gateway. Second, no agent is needed on the resource you wish to connect to, allowing for easy remote administration of resources which may not support agents, like third-party appliances. Third, they preserve existing workflows, enabling you to continue using your preferred client software on your local workstation to connect and manage your resources. And finally, IAM and Security Groups can be used to control access, which we discuss in more detail in the next section.

Prior to the launch of EIC Endpoints, AWS offered two key services to help manage access from public address space into a VPC more carefully. First is EC2 Instance Connect, which provides a mechanism that uses IAM credentials to push ephemeral SSH keys to an instance, making long-lived keys unnecessary. However, until now EC2 Instance Connect required a public IP address on your instance when connecting over the Internet. With this launch, you can use EC2 Instance Connect with EIC Endpoints, combining the two capabilities to give you ephemeral-key-based SSH to your instances without exposure to the public Internet. As an alternative to EC2 Instance Connect and EIC Endpoint based connectivity, AWS also offers Systems Manager Session Manager (SSM), which provides agent-based connectivity to instances. SSM uses IAM for authentication and authorization, and is ideal for environments where an agent can be configured to run.

Given that EIC Endpoint enables access to private resources from public IP space, let’s review the security controls and capabilities in more detail before discussing creating your first EIC Endpoint.

Security capabilities and controls

Many AWS customers remotely managing resources inside their VPCs from the Internet still use either public IP addresses on the relevant resources, or at best a bastion host approach combined with long-lived SSH keys. Using public IPs can be locked down somewhat using IGW routes and/or security groups. However, in a dynamic environment those controls can be hard to manage. As a result, careful management of long-lived SSH keys remains the only layer of defense, which isn’t great since we all know that these controls sometimes fail, and so defense-in-depth is important. Although bastion hosts can help, they increase the operational overhead of managing, patching, and maintaining infrastructure significantly.

IAM authorization is required to create the EIC Endpoint and also to establish a connection via the endpoint’s secure tunneling technology. Along with identity-based access controls governing who, how, when, and how long users can connect, more traditional network access controls like security groups can also be used. Security groups associated with your VPC resources can be used to grant/deny access. Whether it’s IAM policies or security groups, the default behavior is to deny traffic unless it is explicitly allowed.

EIC Endpoint meets important security requirements in terms of separation of privileges for the control plane and data plane. An administrator with full EC2 IAM privileges can create and control EIC Endpoints (the control plane). However, they cannot use those endpoints without also having EC2 Instance Connect IAM privileges (the data plane). Conversely, DevOps engineers who may need to use EIC Endpoint to tunnel into VPC resources do not require control-plane privileges to do so. In all cases, IAM principals using an EIC Endpoint must be part of the same AWS account (either directly or by cross-account role assumption). Security administrators and auditors have a centralized view of endpoint activity as all API calls for configuring and connecting via the EIC Endpoint API are recorded in AWS CloudTrail. Records of data-plane connections include the IAM principal making the request, their source IP address, the requested destination IP address, and the destination port. See the following figure for an example CloudTrail entry.

Figure 2 shows a sample cloud trail entry for SSH data-plane connection for an IAMUser. Specific entry:  Figure 2. Partial CloudTrail entry for an SSH data-plane connection

EIC Endpoint supports the optional use of Client IP Preservation (a.k.a Source IP Preservation), which is an important security consideration for certain organizations. For example, suppose the resource you are connecting to has network access controls that are scoped to your specific public IP address, or your instance access logs must contain the client’s “true” IP address. Although you may choose to enable this feature when you create an endpoint, the default setting is off. When off, connections proxied through the endpoint use the endpoint’s private IP address in the network packets’ source IP field. This default behavior allows connections proxied through the endpoint to reach as far as your route tables permit. Remember, no matter how you configure this setting, CloudTrail records the client’s true IP address.

EIC Endpoints strengthen security by combining identity-based authentication and authorization with traditional network-perimeter controls and provides for fine-grained access control, logging, monitoring, and more defense in depth. Moreover, it does all this without requiring Internet-enabling infrastructure in your VPC, minimizing the possibility of unintended access to private VPC resources.

Getting started

Creating your EIC Endpoint

Only one endpoint is required per VPC. To create or modify an endpoint and connect to a resource, a user must have the required IAM permissions, and any security groups associated with your VPC resources must have a rule to allow connectivity. Refer to the following resources for more details on configuring security groups and sample IAM permissions.

The AWS CLI or Console can be used to create an EIC Endpoint, and we demonstrate the AWS CLI in the following. To create an EIC Endpoint using the Console, refer to the documentation.

Creating an EIC Endpoint with the AWS CLI

To create an EIC Endpoint with the AWS CLI, run the following command, replacing [SUBNET] with your subnet ID and [SG-ID] with your security group ID:

aws ec2 create-instance-connect-endpoint \
    --subnet-id [SUBNET] \
    --security-group-id [SG-ID]

After creating an EIC Endpoint using the AWS CLI or Console, and granting the user IAM permission to create a tunnel, a connection can be established. Now we discuss how to connect to Linux instances using SSH. However, note that you can also use the OpenTunnel API to connect to instances via RDP.

Connecting to your Linux Instance using SSH

With your EIC Endpoint set up in your VPC subnet, you can connect using SSH. Traditionally, access to an EC2 instance using SSH was controlled by key pairs and network access controls. With EIC Endpoint, an additional layer of control is enabled through IAM policy, leading to an enhanced security posture for remote access. We describe two methods to connect via SSH in the following.

One-click command

To further reduce the operational burden of creating and rotating SSH keys, you can use the new ec2-instance-connect ssh command from the AWS CLI. With this new command, we generate ephemeral keys for you to connect to your instance. Note that this command requires use of the OpenSSH client. To use this command and connect, you need IAM permissions as detailed here.

Once configured, you can connect using the new AWS CLI command, shown in the following figure:
Figure 3 shows the AWS CLI view if successfully connecting to your instance using the one-click command. When running the command, you are prompted to connect and can access your instance.

Figure 3. AWS CLI view upon successful SSH connection to your instance

To test connecting to your instance from the AWS CLI, you can run the following command where [INSTANCE] is the instance ID of your EC2 instance:

aws ec2-instance-connect ssh --instance-id [INSTANCE]

Note that you can still use long-lived SSH credentials to connect if you must maintain existing workflows, which we will show in the following. However, note that dynamic, frequently rotated credentials are generally safer.

Open-tunnel command

You can also connect using SSH with standard tooling or using the proxy command. To establish a private tunnel (TCP proxy) to the instance, you must run one AWS CLI command, which you can see in the following figure:

Figure 4 shows the AWS CLI view after running the aws ec2-instance-connect open-tunnel command and connecting to your instance.Figure 4. AWS CLI view after running new SSH open-tunnel command, creating a private tunnel to connect to our EC2 instance

You can run the following command to test connectivity, where [INSTANCE] is the instance ID of your EC2 instance and [SSH-KEY] is the location and name of your SSH key. For guidance on the use of SSH keys, refer to our documentation on Amazon EC2 key pairs and Linux instances.

ssh ec2-user@[INSTANCE] \
    -i [SSH-KEY] \
    -o ProxyCommand='aws ec2-instance-connect open-tunnel \
    --instance-id %h'

Once we have our EIC Endpoint configured, we can SSH into our EC2 instances without a public IP or IGW using the AWS CLI.

Conclusion

EIC Endpoint provides a secure solution to connect to your instances via SSH or RDP in private subnets without IGWs, public IPs, agents, and bastion hosts. By configuring an EIC Endpoint for your VPC, you can securely connect using your existing client tools or the Console/AWS CLI. To learn more, visit the EIC Endpoint documentation.

Discover How AWS Designed Silicon Fuels Customer Outcomes at AWS Silicon Innovation Day

Post Syndicated from Irshad Buchh original https://aws.amazon.com/blogs/aws/discover-how-aws-designed-silicon-fuels-customer-outcomes-at-aws-silicon-innovation-day/

We hope you will join us on Wednesday, June 21, for a free-to-attend online event, AWS Silicon Innovation Day. AWS will stream the event simultaneously across multiple platforms, including LinkedIn Live, Twitter, YouTube, and Twitch.

AWS Silicon Innovation Day is a one-day virtual event on June 21, 2023, that will allow you to better understand AWS Silicon and how you can use AWS’s unique Amazon EC2 chip offerings to your benefit. AWS has designed and developed purpose-built silicon specifically for the cloud.

During this event, you will have the opportunity to hear directly from senior leaders at AWS. Our panel of lead architects, engineers, customers, and analysts will provide insights into our silicon journey. Through deep dives into our cutting-edge silicon design and customer success stories, the panel will provide insights on security enhancements and cost-saving opportunities. Here are some of the highlights you can expect from this event.

Leadership session – To kick off the day, we have a Leadership session featuring Dave Brown, VP of Amazon EC2 and Dr. Ruba Borno, VP of WW Channels and Alliances joining us on stage. Dave will engage in a discussion with Ruba about how you can benefit from the innovation AWS delivers with its silicon technology.

AI/ML session – Gary Szilagyi, VP of Annapurna Labs will discuss with Nafea Bshara, co-founder of Annapurna Labs the utilization of chipset development by his team to create specialized chips for Generative AI, CPU, and the AWS Nitro system. He will highlight how you can harness the Annapurna mindset to develop not only CPUs but also tailor-made chips with specific purposes in mind.

Customer session – Jeff Barr, VP of AWS Evangelism, and Tiffany Wissner, Director of Product Marketing, will delve into insights from our customers. They will share anecdotes and experiences gathered from various sources, such as re:Invent, summits, and developer events, where you have expressed how you harnessed AWS silicon to drive your own remarkable innovations.

Networking session – JR Rivers, Senior Principal Engineer, and Madhura Kale, Senior Product Manager will shed light on the impact of silicon innovation, not only on the benefits you experience using our CPUs, GPUs, or Nitro System, but also on the transformation of AWS’s network infrastructure. They will delve into the realm of networking advancements, showcasing some of the latest innovations and highlighting the instrumental role played by AWS silicon in powering these developments.

Arm and Nitro Innovation session – Anthony Liguori, VP and Fellow, Nitro System architecture will be joined by Ali Saidi, Director of Annapurna Labs to discuss harnessing the power of hardware and software in tandem to drive the development of cutting-edge silicon technologies.

Analyst and Executive session – Raj Pai, VP of Amazon EC2 Product Management will engage in a conversation with an analyst, delving into the realm of silicon innovation in the cloud.

Join us for Silicon Innovation Day Wednesday June 21 9:00am - 4:00pm PDT

No advance registration is needed to participate in AWS Silicon Innovation Day, but you can add an event reminder to your calendar by registering on the event page. We sincerely hope that you will join us in embracing the excitement and seizing the valuable learning opportunities at this new event!

Meet you there.

— Irshad

Disaster Recovery for Oracle Database on Amazon EC2 with Fast-Start Failover

Post Syndicated from Harshad Gohil original https://aws.amazon.com/blogs/architecture/disaster-recovery-for-oracle-database-on-amazon-ec2-with-fast-start-failover/

High availability is non-negotiable for organizations today to prevent business-critical application disruptions. Enterprises must prioritize database scalability and availability to avoid downtime in their databases, network, servers, or storage environments.

For organizations that want to avoid required application changes, Oracle Real Application Clusters (RAC) is an option for providing high availability and scalability to the Oracle database. While the RAC feature is not supported by Oracle databases on Amazon Elastic Compute Cloud (Amazon EC2), Oracle Active Data Guard helps achieve high availability on AWS cloud.

The Oracle Data Guard feature helps customers survive disasters and data corruption while creating, maintaining, and managing one or more synchronized standby databases. But further, configuring Oracle Data Guard Fast-Start Failover (FSFO) helps achieve high availability.

In this blog post, we provide an architectural solution to achieve database high availability when running Oracle Database on Amazon EC2 with Oracle Data Guard along with Fast-Start Failover to address Availability Zones (AZs) or Amazon EC2 instance failures. We also introduce the steps you can take to make database failover happen without manual intervention, and offer recommendations for cross-Region disaster recovery.

Solution overview

Let’s explore this solution by discussing the architecture and two alternate options for securing high availability using Oracle Data Guard, along with the advantages and limitations of each. We will then offer a walkthrough of steps to make database failover happen without manual intervention.

Oracle high availability using Oracle Data Guard with multi-AZ and multi-Region with multi-AZ setup

This architecture is recommended to maintain high availability for Oracle databases on Amazon EC2 with protection against Amazon EC2 service outages in a Region. A disaster recovery environment and higher resiliency are provided after an Amazon EC2 service outage. This protects against Amazon EC2 service outages in an AWS Region and maintains resiliency due to the multi-AZ setup in a secondary Region.

In this architecture, Oracle Data Guard Fast Sync replication exists between the Primary database in AZ 1 in Region A, with standbys in AZ 2 Region A (Fast Sync), AZ1 in Region B (ASYNC), and AZ2 in Region B (ASYNC). There is an asynchronous cascading replication setup between standby databases to avoid network latency issues across regions.

Should Region A experience an Amazon EC2 service outage, the Oracle observer, a client software that monitors Oracle Data Guard and initiate failover to the Standby database in Region B. Applications can continue to connect to the database resulting in high availability with limited/minimal data loss based on the data change rate amount, as in Figure 1.

Oracle with cascading standby databases across regions

Figure 1. Oracle with cascading standby databases across regions

Using Oracle RedoRoutes, the default behavior of Data guard can be controlled and it can be set using the following example during setup.

Oracle RedoRoutes setup example:

dgmgrl > edit database DB_1A set property RedoRoutes= ‘ (LOCAL: DB_1B FASTSYNC PRIORITY=1, DB_2A ASYNC PRIORITY=2,DB_2B ASYNC PRIORITY=3)) (DB_1B: (DB_2A ASYNC PRIORITY=1, DB_2B ASYNC PRIORITY=2)) (DB_2A: DB_1B ASYNC) (DB_2B: DB_1B ASYNC)’

dgmgrl > edit database DB_1B set property RedoRoutes= ‘(LOCAL: (DB_1A FASTSYNC PRIORITY=1, DB_2A ASYNC PRIORITY=2,DB_2B ASYNC PRIORITY=3))(DB_1A: (DB_2A ASYNC PRIORITY=1, DB_2B ASYNC PRIORITY=2)) ‘

dgmgrl > edit database DB_1B set property RedoRoutes= ‘(LOCAL: (DB_2B FASTSYNC PRIORITY=1, DB_1A ASYNC PRIORITY=2, DB_1B ASYNC PRIORITY=3))(DB_2B: (DB_1A ASYNC PRIORITY=1, DB_1B ASYNC PRIORITY=2)) (DB_1A: DB_2B ASYNC)(DB_1B: DB_2B ASYNC )’

dgmgrl > edit database DB_1B set property RedoRoutes= ‘(LOCAL: (DB_2A FASTSYNC PRIORITY=1, DB_1A ASYNC PRIORITY=2, DB_1B ASYNC PRIORITY=3))(DB_2A: (DB_1A ASYNC PRIORITY=1, DB_1B ASYNC PRIORITY=2))’

For more information on Oracle RedoRoutes setup for Oracle Cascading Standby, refer to this step-by-step configuration documentation.

Database failover with Amazon Route 53 and Oracle Data Guard

The following walkthrough defines the steps you can take to make database failover happen without manual intervention using Amazon Route 53 and Oracle Data Guard.

Prerequisites

Before getting started, review the following prerequisites for this solution:

Walkthrough

Step 1. Create Oracle Database Service

For applications to connect without manual intervention on event of failure, we recommend creating an Oracle database service using the Oracle DBMS_Package called DBMS_SERVICE.

exec dbms_service.CREATE_SERVICE(SERVICE_NAME=>'DB_SERVICE_FOR_APP', NETWORK_NAME=>'DB_SERVICE_FOR_APP');

exec dbms_service.START_SERVICE('DB_SERVICE_FOR_APP');

Step 2. Network configuration

Applications can connect to the database seamlessly without manual intervention in an event of a failover from the Primary database to Standby using the Oracle Transparent Application Failover (TAF) approach, though TAF requires updating application connection strings in case of a host IP change.

The following approach using Amazon Route 53 is recommended for added flexibility and scalability. Route 53 has DNS A records that map to the database instance IPs and CNAME records that can redirect DNS queries to A records. The following depicts the DNS mapping. The CNAME, along with the database service name, can be used by the application in its network configuration.

Database_Name =
 (DESCRIPTION =
    (ADDRESS_LIST =
       (ADDRESS = (PROTOCOL = TCP)(HOST = <db_cname>)(PORT = 1521))
   (connect_data = 
       (service_name = <db_service_name>)
   )) )

To update the CNAME in Route 53 to map to the Primary host automatically in the event of failure, follow these steps.

Step 3. Route 53 setup

Create a script named route53update.sh and place it on the database hosts using the following code.

#!/bin/bash

export ORACLE_HOME="<<change>> "

export LD_LIBRARY_PATH=$ORACLE_HOME/lib

export PATH=$ORACLE_HOME/bin:$PATH:/usr/local/bin:/usr/bin

LOG_FILE="/tmp/switch_dns_$$.log"

DNS_DOMAIN="<<change>> "

ACTIVE_DB_CNAME="<<change>> "

HOSTED_ZONE_ID="<<change>> "

TTL="<<change>> "

update_dns () {

TMPFILE="/tmp/route53_dns_$$.log"

 cat > ${TMPFILE} << EOF

    {

      "Comment":"Updating DNS of record ${1}.${DNS_DOMAIN}",

      "Changes":[

        {

          "Action":"UPSERT",

          "ResourceRecordSet":{

            "ResourceRecords":[

              {

                "Value":"$2"

              }

            ],

            "Name":"${1}.${DNS_DOMAIN}.",

            "Type":"CNAME",

            "TTL":$TTL

          }

        }

      ]

    }

EOF

  /usr/local/bin/aws route53 change-resource-record-sets \

        --hosted-zone-id $HOSTED_ZONE_ID \

        --change-batch file://"$TMPFILE" >> "$LOG_FILE"

}

prim_uniq_sid=`$ORACLE_HOME/bin/sqlplus -s  / as sysdba <<EOF

set feedback off echo off lines 2000 head off

select upper(db_unique_name) from  v\\$dataguard_config where DEST_ROLE='PRIMARY DATABASE';

EOF`

prim_uniq_sid=`echo $prim_uniq_sid| sed 's/^[ \t]*//;s/[ \t]*$//'`

host_current=`$ORACLE_HOME/bin/tnsping ${prim_uniq_sid}|sed -n 's/\(.*Host\)\([^)]*\)\(.*\)/\2/pi' |sed 's/=//g'|sed 's/^[ \t]*//;s/[ \t]*$//'`

dns_current_host=`/usr/local/bin/aws route53 list-resource-record-sets --hosted-zone-id $HOSTED_ZONE_ID --query  "ResourceRecordSets[?Name == '${ACTIVE_DB_CNAME}.${DNS_DOMAIN}.'].ResourceRecords" --output text`

if [ "$host_current" != "$dns_current_host" ]; then

        update_dns ${ACTIVE_DB_CNAME} $host_current

fi

Step 4. Database job setup

Create a job in the Oracle Primary database to execute the shell script just introduced to initiate in the event of failover using the following code.

begin
  dbms_scheduler.create_job
  (
    job_name             => 'route53update',
    job_type             => 'executable',
    number_of_arguments  => 0,
    job_action           => '/<<location of script>>/ route53update.sh',
    auto_drop            => false
  );

  dbms_scheduler.enable('route53update');
end;
/

Step 5. Database trigger setup

In an event of a failure, the Primary will failover and the Standby starts up as the new Primary. A trigger needs to be created on the Primary database to execute the job on any failover to update the Route53 CNAME using the following code.

create or replace trigger SYS.Update_Route53_Record
AFTER STARTUP ON DATABASE
DECLARE
db_role varchar2(16);
db_mode varchar2(20);BEGIN
select database_role, open_mode into db_role, db_mode from v$database;
if db_role = 'PRIMARY' then
dbms_scheduler.run_job('route53update') ;
END IF;
END;
/

Alternate Option 1: Single Region with multi-AZ

This option is a minimum recommended configuration to maintain high availability for Oracle databases on Amazon EC2 for customers who do not have a multi-region setup.

  • Advantage: Protects against Amazon EC2 service outage in a single AZ.
  • Limitation: Does not protect against Amazon EC2 service outages in a single Region.

In this architecture, Oracle Data Guard Fast Sync replication exists between the Oracle database instance in a multi-AZ setup with the Primary database (Read Write) in AZ 1 and the Standby database (Read Only) in AZ 2.

If the primary database is unreachable due to any failure, the observer will failover to the standby database in a different AZ. Applications can continue to connect to the database with zero data loss due to synchronous replication between AZ using the Maximum Availability/Maximum Protection mode setup in Oracle Data Guard. If the primary database is in us-east-1a and standby in us-east-1b, the RedoRoutes property can be defined as follows.

Oracle RedoRoutes setup example:

dgmgrl> edit database DB_1A set property RedoRoutes= '(LOCAL: (DB_1B FASTSYNC)'

dgmgrl>  edit database DB_1B set property RedoRoutes= '(LOCAL: (DB_1A FASTSYNC)'

For more information on how disaster recovery works in the AWS Cloud, visit the Disaster recovery is different in the cloud section of the AWS Well-Architected Framework. For more on Oracle RedoRoutes setup, refer to the Oracle Redo Routing Rules documentation.

Alternate Option 2: Multi-AZ with multi-Region with single AZ

This option is recommended to maintain high availability for an Oracle database on Amazon EC2 for customers who need multi-region availability. It provides protection against the rare unavailability of Amazon EC2 instances in the primary Region, in which case a disaster recovery environment is provided.

  • Advantage: Protects against Amazon EC2 service outages in a 2 AZ or AWS Region.
  • Limitation: Decreased resiliency without high availability on Amazon EC2 service outage in an entire Region

In this architecture, Oracle Data Guard Fast Sync replication exists between the Oracle database instance in multi-AZ within the single Region, with the Primary database in AZ 1 in Region A and Standby database in AZ 2 in Region A. There is an asynchronous replication setup between the Standby database cross-Region.

Asynchronous replication is recommended between Region replication to avoid network latency issue. A cascading standby setup ensures there is no additional performance impact on the primary database to send data to multiple standbys.

If the primary database is unreachable, failover happens between AZs in Region A. In the event of an Amazon EC2 service outage in a Region, failover occurs to Region B, resulting in high availability with minimal data loss based on the data change rate amount. If the primary database is in us-east-1a and standby in us-east-1b (Fast Sync) and us-east-2a (Async), the RedoRoutes property can be defined as follows.

Oracle RedoRoutes setup example:

dgmgrl > edit database DB_1A set property RedoRoutes= '(LOCAL: (DB_1B FASTSYNC PRIORITY=1, DB_2A ASYNC PRIORITY=2))(DB_1B: DB_2A ASYNC)(DB_2A: DB_1B ASYNC)'

dgmgrl > edit database DB_1B set property RedoRoutes= '(LOCAL: (DB_1A FASTSYNC PRIORITY=1, DB_2A ASYNC  PRIORITY=2)) (DB_1A: DB_2A ASYNC)'

dgmgrl > edit database DB_1B set property RedoRoutes= '(LOCAL: (DB_1A FASTSYNC PRIORITY=1, DB_1B ASYNC  PRIORITY=2))'

Cleaning up

The services involved in this solution incur costs. When you’re done using this solution, clean up the following resources:

  • Amazon EC2 instances – Stop or delete (terminate) the Amazon EC2 instances that you provisioned.
  • Route53 – Delete the hosted Zone ID and A records/CNAMEs created.

Conclusion

This blog post demonstrates how high availability and disaster recovery can be achieved for an Oracle database on an Amazon EC2 instance using Oracle Data Guard. Using the architectures in this post, you can achieve zero data loss with the Oracle Fast-Start Failover option within the same Region or cross-Region on Amazon EC2.

You can also use this architecture to replicate data from an Oracle database on Amazon EC2 to an Oracle database hosted outside of the AWS cloud. With Oracle Cascading Standby and Oracle RedoRoutes, you can remove high dependency on the Primary database to improve overall performance.