Tag Archives: Amazon Managed Streaming for Apache Kafka (Amazon MSK)

Optimize traffic costs of Amazon MSK consumers on Amazon EKS with rack awareness

Post Syndicated from Austin Groeneveld original https://aws.amazon.com/blogs/big-data/optimize-traffic-costs-of-amazon-msk-consumers-on-amazon-eks-with-rack-awareness/

Are you incurring significant cross Availability Zone traffic costs when running an Apache Kafka client in containerized environments on Amazon Elastic Kubernetes Service (Amazon EKS) that consume data from Amazon Managed Streaming for Apache Kafka (Amazon MSK) topics?

If you’re not familiar with Apache Kafka’s rack awareness feature, we strongly recommend starting with the blog post on how to Reduce network traffic costs of your Amazon MSK consumers with rack awareness for an in-depth explanation of the feature and how Amazon MSK supports it.

Although the solution described in that post uses an Amazon Elastic Compute Cloud (Amazon EC2) instance deployed in a single Availability Zone to consume messages from an Amazon MSK topic, modern cloud-native architectures demand more dynamic and scalable approaches. Amazon EKS has emerged as a leading platform for deploying and managing distributed applications. The dynamic nature of Kubernetes introduces unique implementation challenges compared to static client deployments. In this post, we walk you through a solution for implementing rack awareness in consumer applications that are dynamically deployed across multiple Availability Zones using Amazon EKS.

Here’s a quick recap of some key Apache Kafka terminology from the referenced blog. An Apache Kafka client consumer will register to read against a topic. A topic is the logical data structure that Apache Kafka organizes data into. A topic is segmented into a single or many partitions. Partitions are the unit of parallelism in Apache Kafka. Amazon MSK provides high availability by replicating each partition of a topic across brokers in different Availability Zones. Because there are replicas of each partition that reside across the different brokers that make up your MSK cluster, Amazon MSK also tracks whether a replica partition is in sync with the most recent data for that partition. This means there is one partition that Amazon MSK recognizes as containing the most up-to-date data, and this is known as the leader partition. The collection of replicated partitions is called in-sync replicas. This list of in-sync replicas is used internally when the cluster needs to elect a new leader partition if the current leader were to become unavailable.

When consumer applications read from a topic, the Apache Kafka protocol facilitates a network exchange to determine which broker currently has the leader partition that the consumer needs to read from. This means that the consumer could be told to read from a broker in a different Availability Zone than itself, leading to cross-zone traffic charge in your AWS account. To help optimize this cost, Amazon MSK supports the rack awareness feature, using which clients can ask an Amazon MSK cluster to provide a replica partition to read from, within the same Availability Zone as the client, even if it isn’t the current leader partition. The cluster accomplishes this by checking for an in-sync replica on a broker within the same Availability Zone as the consumer.

The challenge with Kafka clients on Amazon EKS

In Amazon EKS, the underlying units of computes are EC2 instances that are abstracted as Kubernetes nodes. The nodes are organized into node groups for ease of management, scaling, and grouping of applications on certain EC2 instance types. As a best practice for resilience, the nodes in a node group are spread across multiple Availability Zones. Amazon EKS uses the underlying Amazon EC2 metadata about the Availability Zone that it’s located in, and it injects that information into the node’s metadata during node configuration. In particular, the Availability Zone (AZ ID) is injected into the node metadata.

When an application is deployed in a Kubernetes Pod on Amazon EKS, it goes through a process of binding to a node that meets the pod’s requirements. As shown in the following diagram, when you deploy client applications on Amazon EKS, the pod for the application can be bound to a node with available capacity in any Availability Zone. Also, the pod doesn’t automatically inherit the Availability Zone information from the node that it’s bound to, a piece of information necessary for rack awareness. The following architecture diagram illustrates Kafka consumers running on Amazon EKS without rack awareness.
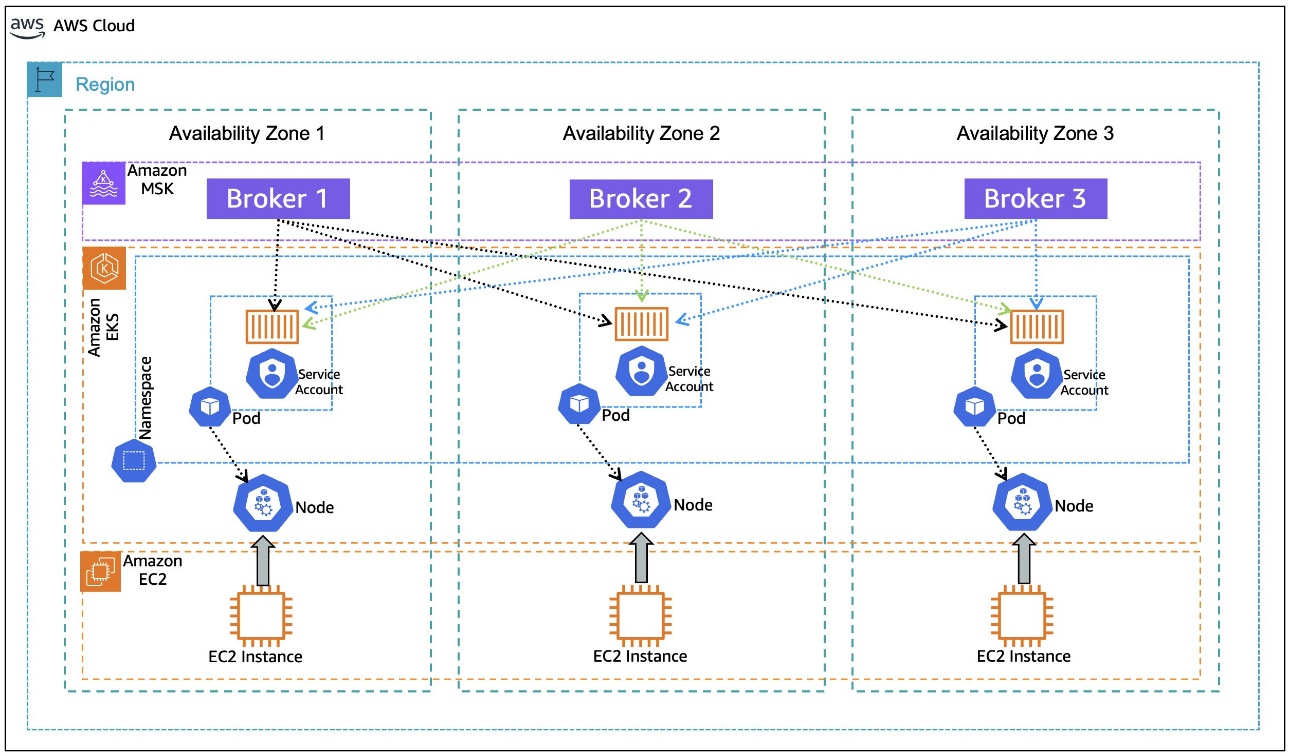
AWS Cloud architecture showing MSK brokers, EKS pods, and EC2 instances in three Availability Zones

To set the client configuration for rack awareness, the pod needs to know what Availability Zone it’s located in, dynamically, as it is bound to a node. During its lifecycle, the same pod can be evicted from the node it was bound to previously and moved to a node in a different Availability Zone, if the matching criteria permit that. Making the pod aware of its Availability Zone dynamically sets the rack awareness parameter client.rack during the initialization of the application container that is encapsulated in the pod.

After rack awareness is enabled on the MSK cluster, what happens if the broker in the same Availability Zone as the client (hosted on Amazon EKS or elsewhere) becomes unavailable? The Apache Kafka protocol is designed to support a distributed data storage system. Assuming customers follow the best practice of implementing a replication factor > 1, Apache Kafka can dynamically reroute the consumer client to the next available in-sync replica on a different broker. This resilience remains consistent even after implementing nearest replica fetching, or rack awareness. Enabling rack awareness optimizes the networking exchange to prefer a partition within the same Availability Zone, but it doesn’t compromise the consumer’s ability to operate if the nearest replica is unavailable.

In this post, we walk you through an example of how to use the Kubernetes metadata label, topology.k8s.aws/zone-id, assigned to each node by Amazon EKS, and use an open source policy engine, Kyverno, to deploy a policy that mutates the pods that are in the binding state to dynamically inject the node’s AZ ID into the pod’s metadata as an annotation, as depicted in the following diagram. This annotation, in turn, is used by the container to create an environment variable that is assigned the pod’s annotated AZ ID information. The environment variable is then used in the container postStart lifecycle hook to generate the Kafka client configuration file with rack awareness setting. The following architecture diagram illustrates Kafka consumers running on Amazon EKS with rack awareness.
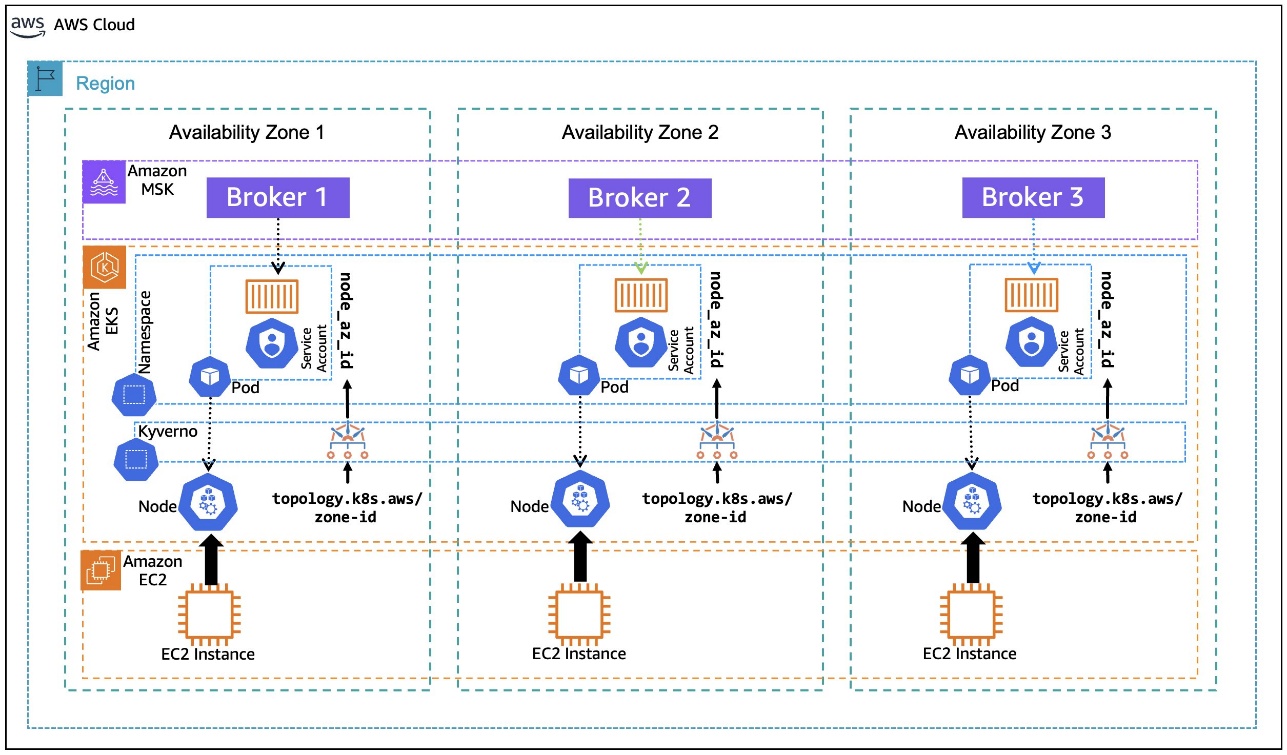
AWS architecture with MSK, EKS, Kyverno, and EC2 across three Availability Zones, detailing topology

Solution Walkthrough

Prerequisites

For this walkthrough, we use AWS CloudShell to run the scripts that are provided inline as you progress. For a smooth experience, before getting started, make sure to have kubectl and eksctl installed and configured in the AWS CloudShell environment, following the installation instructions for Linux (amd64). Helm is also required to be install on AWS CloudShell, using the instructions for Linux.

Also, check if the envsubst tool is installed in your CloudShell environment by invoking:

which envsubst

If the tool isn’t installed, you can install it using the command:

sudo dnf -y install gettext-devel

We also assume you already have an MSK cluster deployed in an Amazon Virtual Private Cloud (VPC) in three Availability Zones with the name MSK-AZ-Aware. In this walkthrough, we use AWS Identity and Access Management (IAM) authentication for client access control to the MSK cluster. If you’re using a cluster in your account with a different name, replace the instances of MSK-AZ-Aware in the instructions.

We follow the same MSK cluster configuration mentioned in the Rack Awareness blog mentioned previously, with some modifications. (Ensure you’ve set replica.selector.class = org.apache.kafka.common.replica.RackAwareReplicaSelector for the reasons discussed there). In our configuration, we add one line: num.partitions = 6. Although not mandatory, this ensures that topics that are automatically created will have multiple partitions to support clearer demonstrations in subsequent sections.

Finally, we use the Amazon MSK Data Generator with the following configuration:

{
"name": "msk-data-generator",
    "config": {
    "connector.class": "com.amazonaws.mskdatagen.GeneratorSourceConnector",
    "genkp.MSK-AZ-Aware-Topic.with": "#{Internet.uuid}",
    "genv.MSK-AZ-Aware-Topic.product_id.with": "#{number.number_between '101','200'}",
    "genv.MSK-AZ-Aware-Topic.quantity.with": "#{number.number_between '1','5'}",
    "genv.MSK-AZ-Aware-Topic.customer_id.with": "#{number.number_between '1','5000'}"
    }
}

Running the MSK Data Generator with this configuration will automatically create a six-partition topic named MSK-AZ-Aware-Topic on our cluster for us, and it will push data to that topic. To follow along with the walkthrough, we recommend and assume that you deploy the MSK Data Generator to create the topic and populate it with simulated data.

Create the EKS cluster

The first step is to install an EKS cluster in the same Amazon VPC subnets as the MSK cluster. You can modify the name of the MSK cluster by changing that environment variable MSK_CLUSTER_NAME if your cluster is created with a different name than suggested. You can also change the Amazon EKS cluster name by changing EKS_CLUSTER_NAME.

The environment variables that we define here are used throughout the walkthrough.

The last step is to update the kubeconfig with an entry for the EKS cluster:

AWS_ACCOUNT=$(aws sts get-caller-identity --output text --query Account)
export AWS_ACCOUNT
export AWS_REGION=${AWS_DEFAULT_REGION}
export MSK_CLUSTER_NAME=MSK-AZ-Aware
export EKS_CLUSTER_NAME=EKS-AZ-Aware
export EKS_CLUSTER_SIZE=3
export K8S_VERSION=1.32
export POD_ID_VERSION=1.3.5
 
MSK_BROKER_SG=$(aws kafka list-clusters \
  --query  'ClusterInfoList[?ClusterName==`'${MSK_CLUSTER_NAME}'`].BrokerNodeGroupInfo.SecurityGroups'  \
  --output text | xargs)
export MSK_BROKER_SG

MSK_BROKER_CLIENT_SUBNETS=$(aws kafka list-clusters \
  --query  'ClusterInfoList[?ClusterName==`'${MSK_CLUSTER_NAME}'`].BrokerNodeGroupInfo.ClientSubnets'  \
  --output text | xargs)
export MSK_BROKER_CLIENT_SUBNETS
 
VPC_ID=$(aws ec2 describe-subnets \
  --subnet-ids "$(echo "${MSK_BROKER_CLIENT_SUBNETS}" | cut -d' ' -f1)" \
  --query 'Subnets[0].VpcId' \
  --output text)
export VPC_ID

EKS_SUBNETS=$(echo ${MSK_BROKER_CLIENT_SUBNETS} | sed 's/ \+/,/g')
export EKS_SUBNETS

# Create a minimal config file for encrypted node volumes
cat > eks-config.yaml << EOF
apiVersion: eksctl.io/v1alpha5
kind: ClusterConfig
metadata:
  name: ${EKS_CLUSTER_NAME}
  region: ${AWS_REGION}
  version: "${K8S_VERSION}"
vpc:
  id: "${VPC_ID}"
  subnets:
    public:
$(for subnet in ${MSK_BROKER_CLIENT_SUBNETS}; do
  AZ=$(aws ec2 describe-subnets --subnet-ids "$subnet" --query 'Subnets[0].AvailabilityZone' --output text)
  echo "      $AZ: { id: $subnet }"
done)
nodeGroups:
  - name: ng1
    instanceType: m5.xlarge
    desiredCapacity: ${EKS_CLUSTER_SIZE}
    minSize: ${EKS_CLUSTER_SIZE}
    maxSize: ${EKS_CLUSTER_SIZE}
    securityGroups:
      attachIDs: ["${MSK_BROKER_SG}"]
    volumeSize: 100
    volumeType: gp3
    volumeEncrypted: true
EOF

eksctl create cluster -f eks-config.yaml

aws eks update-kubeconfig \
  --region "${AWS_REGION}" \
  --name ${EKS_CLUSTER_NAME}

Next, you need to create an IAM policy, MSK-AZ-Aware-Policy, to allow access from the Amazon EKS pods to the MSK cluster. Note here that we’re using MSK-AZ-Aware as the cluster name.

Create a file, msk-az-aware-policy.json, with the IAM policy template:

cat > msk-az-aware-policy.json << EOF
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "kafka-cluster:Connect",
                "kafka-cluster:AlterCluster",
                "kafka-cluster:DescribeCluster",
                "kafka-cluster:DescribeClusterDynamicConfiguration",
                "kafka-cluster:AlterClusterDynamicConfiguration"
            ],
            "Resource": [
                "arn:aws:kafka:${AWS_REGION}:${AWS_ACCOUNT}:cluster/${MSK_CLUSTER_NAME}/*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "kafka-cluster:*Topic*",
                "kafka-cluster:WriteData",
                "kafka-cluster:ReadData"
            ],
            "Resource": [
                "arn:aws:kafka:${AWS_REGION}:${AWS_ACCOUNT}:topic/${MSK_CLUSTER_NAME}/*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "kafka-cluster:AlterGroup",
                "kafka-cluster:DescribeGroup"
            ],
            "Resource": [
                "arn:aws:kafka:${AWS_REGION}:${AWS_ACCOUNT}:group/${MSK_CLUSTER_NAME}/*"
            ]
        }
    ]
}
EOF

To create the IAM policy, use the following command. It first replaces the placeholders in the policy file with values from relevant environment variables, and then creates the IAM policy:

envsubst < msk-az-aware-policy.json | \
xargs -0 -I {} aws iam create-policy \
            --policy-name MSK-AZ-Aware-Policy \
            --policy-document {}

Configure EKS Pod Identity

Amazon EKS Pod Identity offers a simplified experience for obtaining IAM permissions for pods on Amazon EKS. This requires installing an add-on Amazon EKS Pod Identity Agent to the EKS cluster:

eksctl create addon \
  --cluster ${EKS_CLUSTER_NAME} \
  --name eks-pod-identity-agent \
  --version ${POD_ID_VERSION}

Confirm that the add-on has been installed and its status is ACTIVE and that the status of all the pods associated with the add-on is Running.

eksctl get addon \
  --cluster ${EKS_CLUSTER_NAME} \
  --region "${AWS_REGION}" \
  --name eks-pod-identity-agent -o json

kubectl get pods \
  -n kube-system \
  -l app.kubernetes.io/instance=eks-pod-identity-agent

After you’ve installed the add-on, you need to create a pod identity association between a Kubernetes service account and the IAM policy created earlier:

eksctl create podidentityassociation \
  --namespace kafka-ns \
  --service-account-name kafka-sa \
  --role-name EKS-AZ-Aware-Role \
  --permission-policy-arns arn:aws:iam::"${AWS_ACCOUNT}":policy/MSK-AZ-Aware-Policy \
  --cluster ${EKS_CLUSTER_NAME} \
  --region "${AWS_REGION}"

Install Kyverno

Kyverno is an open source policy engine for Kubernetes that allows for validation, mutation, and generation of Kubernetes resources using policies written in YAML, thus simplifying the enforcement of security and compliance requirements. You need to install Kyverno to dynamically inject metadata into the Amazon EKS pods as they enter the binding state to inform them of Availability Zone ID.

In AWS CloudShell, create a file named kyverno-values.yaml. This file defines the Kubernetes RBAC permissions for Kyverno’s Admission Controller to read Amazon EKS node metadata because the default Kyverno (v. 1.13 onwards) settings don’t allow this:

cat > kyverno-values.yaml << EOF
admissionController:
  rbac:
    clusterRole:
      extraResources:
        - apiGroups:
            - ""
          resources:
            - "nodes"
          verbs:
            - get
            - list
            - watch
EOF

After this file is created, you can install Kyverno using helm and providing the values file created in the previous step:

helm repo add kyverno https://kyverno.github.io/kyverno/
helm repo update

helm install kyverno kyverno/kyverno \
  -n kyverno \
  --create-namespace \
  --version 3.3.7 \
  -f kyverno-values.yaml

Starting with Kyverno v 1.13, the Admission Controller is configured to ignore the AdmissionReview requests for pods in binding state. This needs to be changed by editing the Kyverno ConfigMap:

kubectl -n kyverno edit configmap kyverno

The kubectl edit command uses the default editor configured in your environment (in our case Linux VIM).

This will open the ConfigMap in a text editor.

As highlighted in the following screenshot, [Pod/binding,*,*] should be removed from the resourceFilters field for the Kyverno Admission Controller to process AdmissionReview requests for pods in binding state.
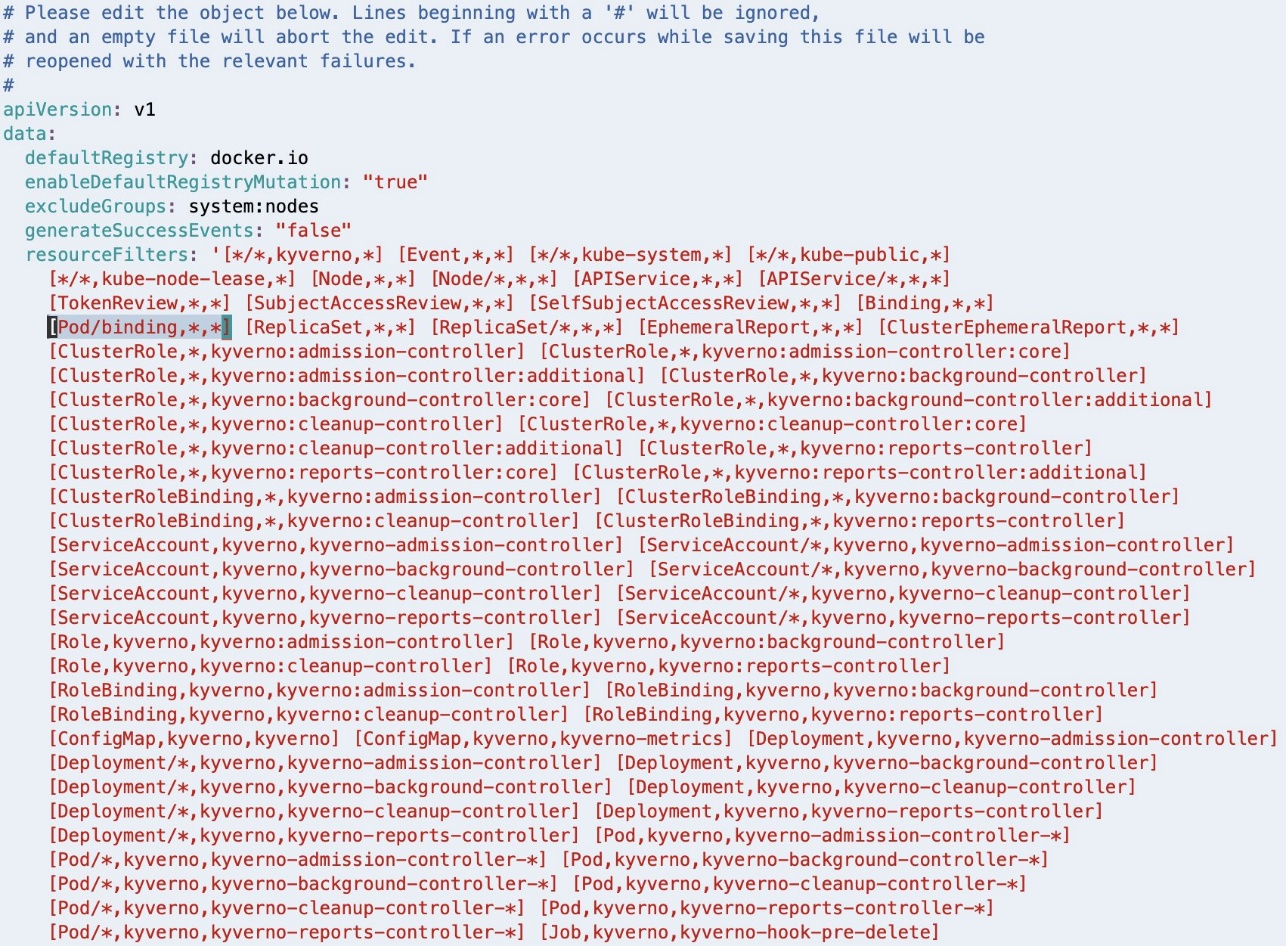
Kubernetes YAML configuration detailing Kyverno policy resource filters and cluster roles

If Linux VIM is your default editor, you can delete the entry using VIM command 18x, meaning delete (or cut) 18 characters from the current cursor position. Save the modified configuration using the VIM command :wq, meaning write (or save) the file and quit.

After deleting, the resourceFilters field should look similar to the following screenshot.
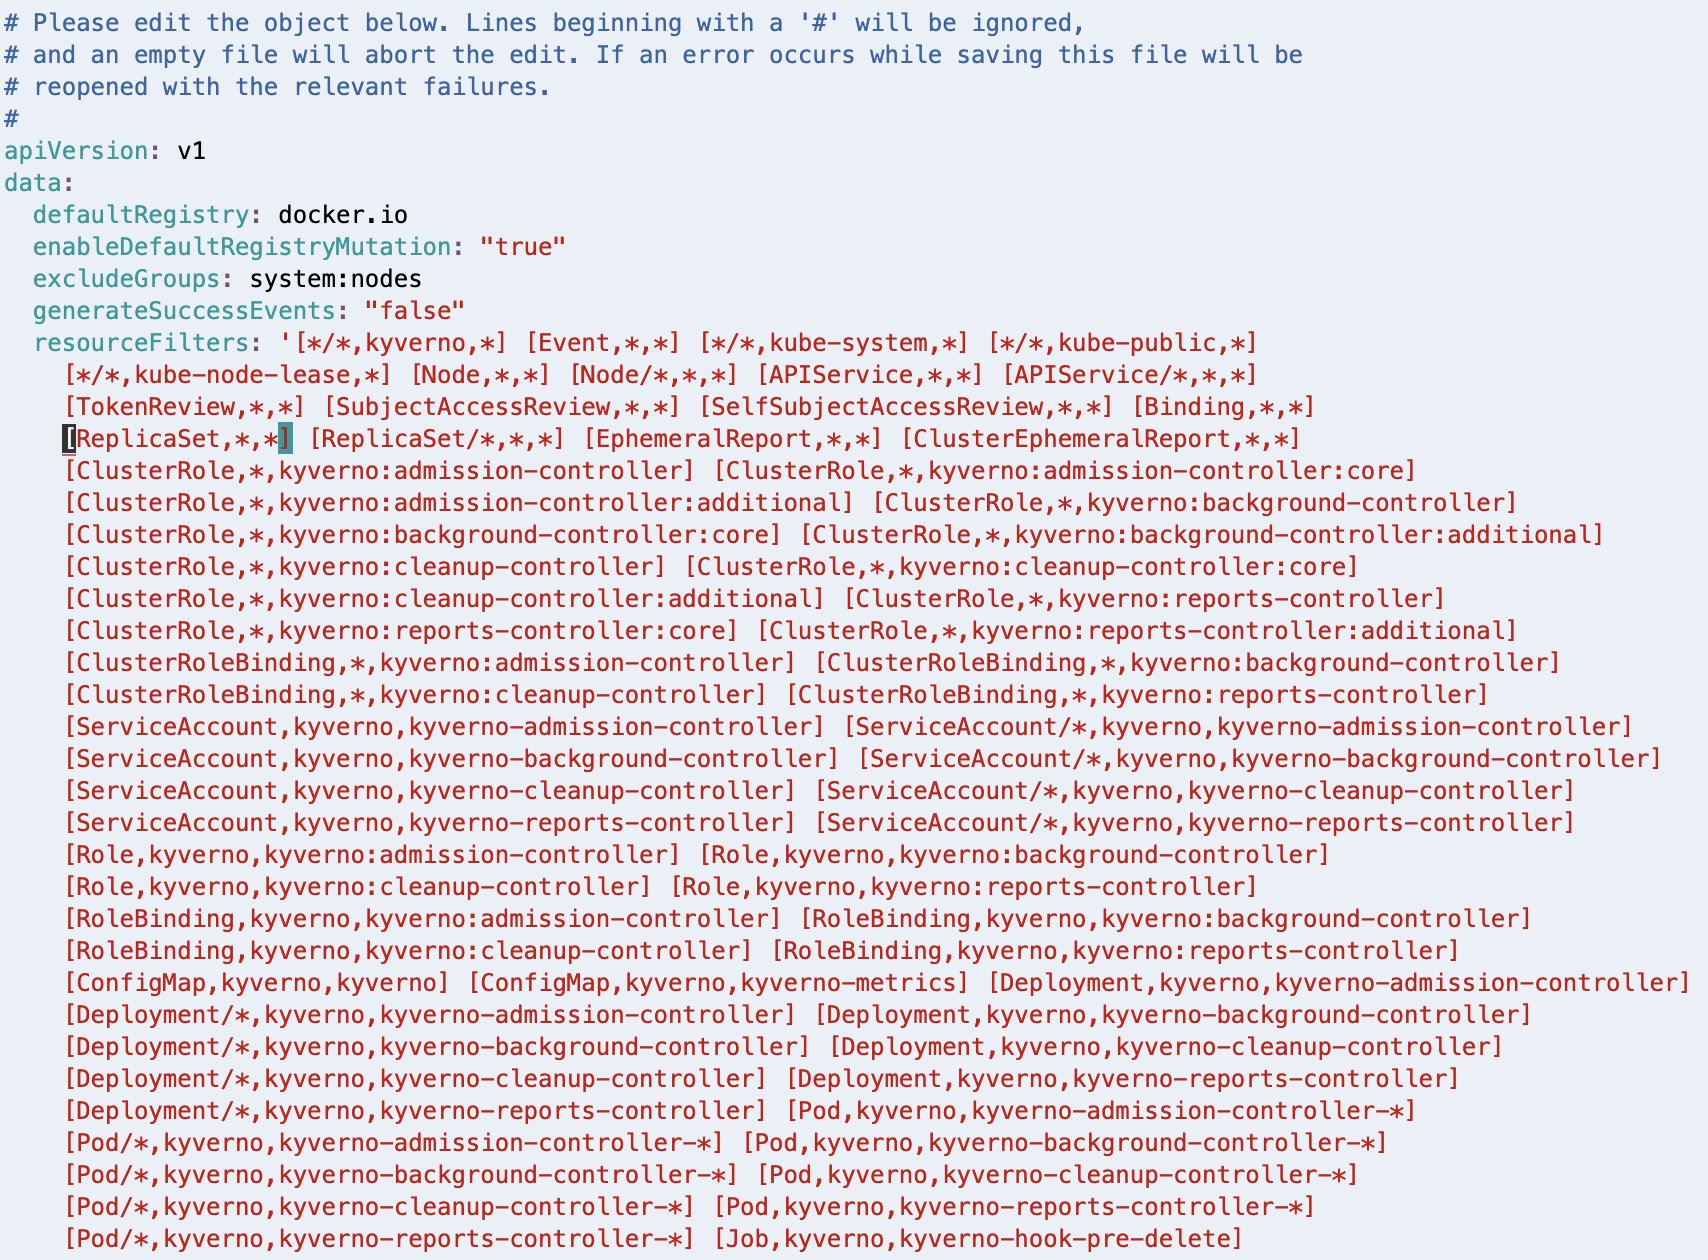
Kubernetes YAML configuration with ReplicaSet resource filter highlighted for Kyverno policy management

If you have a different editor configured in your environment, follow the appropriate steps to achieve a similar outcome.

Configure Kyverno policy

You need to configure the policy that will make the pods rack aware. This policy is adapted from the suggested approach in the Kyverno blog post, Assigning Node Metadata to Pods. Create a new file with the name kyverno-inject-node-az-id.yaml:

cat > kyverno-inject-node-az-id.yaml  << EOF
apiVersion: kyverno.io/v2beta1
kind: ClusterPolicy
metadata:
  name: inject-node-az-id
spec:
  background: false
  rules:
    - name: inject-node-az-id
      match:
        any:
        - resources:
            kinds:
            - Pod/binding
      context:
      - name: node
        variable:
          jmesPath: request.object.target.name
          default: ''
      - name: node_az_id
        apiCall:
          urlPath: "/api/v1/nodes/{{node}}"
          jmesPath: "metadata.labels.\"topology.k8s.aws/zone-id\" || 'empty'"
      mutate:
        patchStrategicMerge:
          metadata:
            annotations:
              node_az_id: "{{ node_az_id }}"
EOF

It instructs Kyverno to watch for pods in binding state. After Kyverno receives the AdmissionReview request for a pod, it sets the variable node to the name of the node to which the pod is being bound. It also sets another variable node_az_id to the Availability Zone ID by calling the Kubernetes API /api/v1/nodes/node to get the node metadata label topology.k8s.aws/zone-id. Finally, it defines a mutate rule to inject the obtained AZ ID into the pod’s metadata as an annotation node_az_id.
After you’ve created the file, apply the policy using the following command:

kubectl apply -f kyverno-inject-node-az-id.yaml

Deploy a pod without rack awareness

Now let’s visualize the problem statement. To do this, connect to one of the EKS pods and check how it interacts with the MSK cluster when you run a Kafka consumer from the pod.

First, get the bootstrap string of the MSK cluster. Look up the Amazon Resource Names (ARNs) of the MSK cluster:

MSK_CLUSTER_ARN=$(
    aws kafka list-clusters \
      --query 'ClusterInfoList[?ClusterName==`'${MSK_CLUSTER_NAME}'`].ClusterArn' \
      --output text)
export MSK_CLUSTER_ARN

Using the cluster ARN, you can get the bootstrap string with the following command:

BOOTSTRAP_SERVER_LIST=$(
    aws kafka get-bootstrap-brokers \
        --cluster-arn "${MSK_CLUSTER_ARN}" \
        --query 'BootstrapBrokerStringSaslIam' \
        --output text)
export BOOTSTRAP_SERVER_LIST

Create a new file named kafka-no-az.yaml:

cat > kafka-no-az.yaml << EOF
apiVersion: v1
kind: Namespace
metadata:
 name: kafka-ns
---
apiVersion: v1
kind: ServiceAccount
metadata:
 name: kafka-sa
 namespace: kafka-ns
automountServiceAccountToken: false
---
apiVersion: apps/v1
kind: Deployment
metadata:
  name: kafka-no-az
  namespace: kafka-ns
  labels:
    app: kafka-no-az
  annotations:
    node_az_id: ''
spec:
  replicas: 3
  selector:
    matchLabels:
      app: kafka-no-az
  template:
    metadata:
      labels:
        app: kafka-no-az
    spec:
      serviceAccountName: kafka-sa
      containers:
      - image: bitnami/kafka:3.8.0
        name: kafka-no-az
        command: ["/bin/sh", "-ec", "while :; do echo '.'; sleep 5 ; done"]
        env:
        - name: BootstrapServerString
          value: ${BOOTSTRAP_SERVER_LIST}
        - name: MSK_TOPIC
          value: "MSK-AZ-Aware-Topic"
        - name: KAFKA_HOME
          value: /opt/bitnami/kafka
        - name: KAFKA_BIN
          value: /opt/bitnami/kafka/bin
        - name: KAFKA_CONFIG
          value: /opt/bitnami/kafka/config
        - name: KAFKA_LIBS
          value: /opt/bitnami/kafka/libs
        - name: KAFKA_LOG4J_OPTS
          value: "-Dlog4j.configuration=file:/opt/bitnami/kafka/config/log4j.properties"
        lifecycle:
          postStart:
            exec:
              command: 
              - "sh"
              - "-c"
              - |
                export KAFKA_HOME=/opt/bitnami/kafka
                export KAFKA_BIN=\${KAFKA_HOME}/bin
                export KAFKA_CONFIG=\${KAFKA_HOME}/config
                cat > \${KAFKA_CONFIG}/client.properties << EOF1
                security.protocol=SASL_SSL
                sasl.mechanism=AWS_MSK_IAM
                sasl.jaas.config=software.amazon.msk.auth.iam.IAMLoginModule required;
                sasl.client.callback.handler.class=software.amazon.msk.auth.iam.IAMClientCallbackHandler
                EOF1
                
                cat >> \${KAFKA_CONFIG}/log4j.properties << EOF2
                #
                # Enable logging of Kafka Client to stderr
                #
                log4j.rootLogger=WARN, stderr
                log4j.logger.org.apache.kafka.clients.consumer.internals.AbstractFetch=DEBUG
                log4j.appender.stderr=org.apache.log4j.ConsoleAppender
                log4j.appender.stderr.layout=org.apache.log4j.PatternLayout
                log4j.appender.stderr.layout.ConversionPattern=[%d] %p %m (%c)%n
                log4j.appender.stderr.Target=System.err
                EOF2
                cd \${KAFKA_HOME}/libs
                /usr/bin/curl -sS -L https://github.com/aws/aws-msk-iam-auth/releases/download/v2.2.0/aws-msk-iam-auth-2.2.0-all.jar --output \${KAFKA_LIBS}/aws-msk-iam-auth-2.2.0-all.jar
EOF

This pod manifest doesn’t make use of the Availability Zone ID injected into the metadata annotation and hence doesn’t add client.rack to the client.properties configuration.

Deploy the pods using the following command:

kubectl apply -f kafka-no-az.yaml

Run the following command to confirm that the pods have been deployed and are in the Running state:

kubectl -n kafka-ns get pods

Select a pod id from the output of the previous command, and connect to it using:

kubectl -n kafka-ns exec -it POD_ID -- sh

Run the Kafka consumer:

"${KAFKA_BIN}"/kafka-console-consumer.sh \
  --bootstrap-server  "${BootstrapServerString}" \
  --consumer.config  "${KAFKA_CONFIG}"/client.properties \
  --topic "${MSK_TOPIC}" \
  --from-beginning /tmp/non-rack-aware-consumer.log 2>&1 &

This command will dump all the resulting logs into the file, non-rack-aware-consumer.log. There’s a lot of information in those logs, and we encourage you to open them and take a deeper look. Next, examine the EKS pod in action. To do this, run the following command to tail the file to view fetch request results to the MSK cluster. You’ll notice a handful of meaningful logs to review as the consumer access various partitions of the Kafka topic:

grep -E "DEBUG.*Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-[0-9]+" /tmp/rack-aware-consumer.log | tail -5

Observe your log output, which should look similar to the following:

[2025-03-12 23:59:05,308] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-24102] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-3 at position FetchPosition{offset=100, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-12 23:59:05,308] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-24102] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-0 at position FetchPosition{offset=83, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-12 23:59:05,542] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-24102] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-5 at position FetchPosition{offset=100, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-1.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 1 rack: use1-az4)], epoch=0}} to node b-1.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 1 rack: use1-az4) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-12 23:59:05,542] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-24102] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-2 at position FetchPosition{offset=107, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-1.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 1 rack: use1-az4)], epoch=0}} to node b-1.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 1 rack: use1-az4) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-12 23:59:05,720] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-24102] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-4 at position FetchPosition{offset=84, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-3.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 3 rack: use1-az2)], epoch=0}} to node b-3.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 3 rack: use1-az2) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-12 23:59:05,720] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-24102] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-1 at position FetchPosition{offset=85, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-3.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 3 rack: use1-az2)], epoch=0}} to node b-3.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 3 rack: use1-az2) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-12 23:59:05,811] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-24102] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-3 at position FetchPosition{offset=100, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-12 23:59:05,811] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-24102] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-0 at position FetchPosition{offset=83, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)

You’ve now connected to a specific pod in the EKS cluster and run a Kafka consumer to read from the MSK topic without rack awareness. Remember that this pod is running within a single Availability Zone.

Reviewing the log output, you find rack: values as use1-az2, use1-az4, and use1-az6 as the pod makes calls to different partitions of the topic. These rack values represent the Availability Zone IDs that our brokers are running within. This means that our EKS pod is creating networking connections to brokers across three different Availability Zones, which would be accruing networking charges in our account.

Also notice that you have no way to check which node, and therefore Availability Zone, this EKS pod is running in. You can observe in the logs that it’s calling to MSK brokers in different Availability Zones, but there is no way to know which broker is in the same Availability Zone as the EKS pod you’ve connected to. Delete the deployment when you’re done:

kubectl -n kafka-ns delete -f kafka-no-az.yaml

Deploy a pod with rack awareness

Now that you have experienced the consumer behavior without rack awareness, you need to inject the Availability Zone ID to make your pods rack-aware.

Create a new file named kafka-az-aware.yaml:

cat > kafka-az-aware.yaml << EOF
apiVersion: v1
kind: Namespace
metadata:
 name: kafka-ns
---
apiVersion: v1
kind: ServiceAccount
metadata:
 name: kafka-sa
 namespace: kafka-ns
automountServiceAccountToken: false
---
apiVersion: apps/v1
kind: Deployment
metadata:
  name: kafka-az-aware
  namespace: kafka-ns
  labels:
    app: kafka-az-aware
  annotations:
    node_az_id: ''
spec:
  replicas: 3
  selector:
    matchLabels:
      app: kafka-az-aware
  template:
    metadata:
      labels:
        app: kafka-az-aware
    spec:
      serviceAccountName: kafka-sa
      containers:
      - image: bitnami/kafka:3.8.0
        name: kafka-az-aware
        command: ["/bin/sh", "-ec", "while :; do echo '.'; sleep 5 ; done"]
        env:
        - name: BootstrapServerString
          value: ${BOOTSTRAP_SERVER_LIST}
        - name: MSK_TOPIC
          value: "MSK-AZ-Aware-Topic"
        - name: KAFKA_HOME
          value: /opt/bitnami/kafka
        - name: KAFKA_BIN
          value: /opt/bitnami/kafka/bin
        - name: KAFKA_CONFIG
          value: /opt/bitnami/kafka/config
        - name: KAFKA_LIBS
          value: /opt/bitnami/kafka/libs
        - name: KAFKA_LOG4J_OPTS
          value: "-Dlog4j.configuration=file:/opt/bitnami/kafka/config/log4j.properties"
        - name: NODE_AZ_ID
          valueFrom:
            fieldRef:
              fieldPath: metadata.annotations['node_az_id']
        lifecycle:
          postStart:
            exec:
              command: 
              - "sh"
              - "-c"
              - |
                export KAFKA_HOME=/opt/bitnami/kafka
                export KAFKA_BIN=\${KAFKA_HOME}/bin
                export KAFKA_CONFIG=\${KAFKA_HOME}/config
                cat > \${KAFKA_CONFIG}/client.properties << EOF1
                security.protocol=SASL_SSL
                sasl.mechanism=AWS_MSK_IAM
                sasl.jaas.config=software.amazon.msk.auth.iam.IAMLoginModule required;
                sasl.client.callback.handler.class=software.amazon.msk.auth.iam.IAMClientCallbackHandler
                EOF1
                if [ \$NODE_AZ_ID ]
                then
                  echo "client.rack=\$NODE_AZ_ID" >> \${KAFKA_CONFIG}/client.properties
                fi
                
                cat >> \${KAFKA_CONFIG}/log4j.properties << EOF2
                #
                # Enable logging of Kafka Client to stderr
                #
                log4j.rootLogger=WARN, stderr
                log4j.logger.org.apache.kafka.clients.consumer.internals.AbstractFetch=DEBUG
                log4j.appender.stderr=org.apache.log4j.ConsoleAppender
                log4j.appender.stderr.layout=org.apache.log4j.PatternLayout
                log4j.appender.stderr.layout.ConversionPattern=[%d] %p %m (%c)%n
                log4j.appender.stderr.Target=System.err
                EOF2
                
                /usr/bin/curl -sS -L https://github.com/aws/aws-msk-iam-auth/releases/download/v2.2.0/aws-msk-iam-auth-2.2.0-all.jar --output \${KAFKA_LIBS}/aws-msk-iam-auth-2.2.0-all.jar
EOF

As you can observe, the pod manifest defines an environment variable NODE_AZ_ID, assigning it the value from the pod’s own metadata annotation node_az_id that was injected by Kyverno. The manifest then uses the pod’s postStart lifecycle script to add client.rack into the client.properties configuration, setting it equal to the value in the environment variable NODE_AZ_ID.

Deploy the pods using the following command:

kubectl apply -f kafka-az-aware.yaml

Run the following command to confirm that the pods have been deployed and are in the Running state:

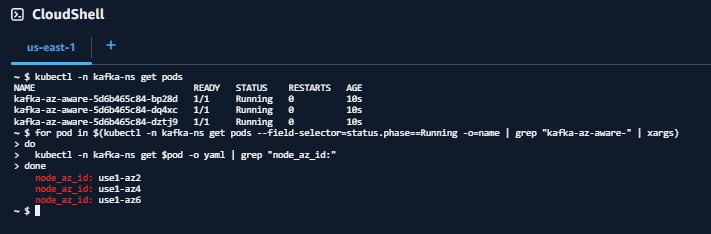
kubectl -n kafka-ns get pods

Verify that Availability Zone Ids have been injected into the pods

for pod in $(kubectl -n kafka-ns get pods --field-selector=status.phase==Running -o=name | grep "pod/kafka-az-aware-" | xargs)
do
  kubectl -n kafka-ns get "$pod" -o yaml | grep "node_az_id:"
done

Your output should look similar to:

node_az_id: use1-az2
node_az_id: use1-az4
node_az_id: use1-az6

Or:

AWS CloudShell showing Kafka namespace pods and node assignments in Kubernetes cluster

Select a pod id from the output of the get pods command and shell-in to it.

kubectl -n kafka-ns exec -it POD_ID -- sh

The output of the get $pod command matches the order of results from the get pods command. This matching will help you understand what Availability Zone your pod is running in so you can compare it to log outputs later.

After you’ve connected to your pod, run the Kafka consumer:

"${KAFKA_BIN}"/kafka-console-consumer.sh \
  --bootstrap-server  "${BootstrapServerString}" \
  --consumer.config  "${KAFKA_CONFIG}"/client.properties \
  --topic "${MSK_TOPIC}" \
  --from-beginning /tmp/non-rack-aware-consumer.log 2>&1 &

Similar to before, this command will dump all the resulting logs into the file, rack-aware-consumer.log. You create a new file so there’s no overlap between the Kafka consumers you’ve run. There’s a lot of information in those logs, and we encourage you to open them and take a deeper look. If you want to see the rack awareness of your EKS pod in action, run the following command to tail the file to view fetch request results to the MSK cluster. You can observe a handful of meaningful logs to review here as the consumer access various partitions of the Kafka topic:

grep -E "DEBUG.*Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-[0-9]+" /tmp/rack-aware-consumer.log | tail -5

Observe your log output, which should look similar to the following:

[2025-03-13 00:47:51,695] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-86303] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-5 at position FetchPosition{offset=527, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-1.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 1 rack: use1-az4)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-13 00:47:51,695] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-86303] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-4 at position FetchPosition{offset=509, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-3.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 3 rack: use1-az2)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-13 00:47:51,695] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-86303] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-3 at position FetchPosition{offset=527, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-13 00:47:51,695] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-86303] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-2 at position FetchPosition{offset=522, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-1.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 1 rack: use1-az4)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-13 00:47:51,695] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-86303] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-1 at position FetchPosition{offset=533, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-3.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 3 rack: use1-az2)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)
[2025-03-13 00:47:51,695] DEBUG [Consumer clientId=console-consumer, groupId=console-consumer-86303] Added read_uncommitted fetch request for partition MSK-AZ-Aware-Topic-0 at position FetchPosition{offset=520, offsetEpoch=Optional[0], currentLeader=LeaderAndEpoch{leader=Optional[b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6)], epoch=0}} to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)

For each log line, you can now observe two rack: values. The first rack: value shows the current leader, the second rack: shows the rack that is being used to fetch messages.

For example, look at MSK-AZ-Aware-Topic-5. The leader is identified as rack: use1-az4, but the fetch request is sent to use1-az6 as indicated by to node b-2.mskazaware.hxrzlh.c6.kafka.us-east-1.amazonaws.com:9098 (id: 2 rack: use1-az6) (org.apache.kafka.clients.consumer.internals.AbstractFetch)

You’ll notice something similar in all other log lines. The fetch is always to the broker in use1-az6, which maps to our expectation, given the pod we connected to was in this Availability Zone.

Congratulations! You’re consuming from the closest replica on Amazon EKS.

Clean Up

Delete the deployment when finished:

kubectl -n kafka-ns delete -f kafka-az-aware.yaml

To delete the EKS Pod Identity association:

eksctl delete podidentityassociation \
--cluster ${EKS_CLUSTER_NAME} \
--namespace kafka-ns \
--service-account-name kafka-sa

To delete the IAM policy:

aws iam delete-policy \
  --policy-arn arn:aws:iam::"${AWS_ACCOUNT}":policy/MSK-AZ-Aware-Policy

To delete the EKS cluster:

eksctl delete cluster -n ${EKS_CLUSTER_NAME} --disable-nodegroup-eviction

If you followed along with this post using the Amazon MSK Data Generator, be sure to delete your deployment so it’s no longer attempting to generate and send data after you delete the rest of your resources.

Clean up will depend on which deployment option you used. To read more about the deployment options and the resources created for the Amazon MSK Data Generator, refer to Getting Started in the GitHub repository.

Creating an MSK cluster was a prerequisite of this post, and if you’d like to clean up the MSK cluster as well, you can use the following command:

aws kafka delete-cluster --cluster-arn "${MSK_CLUSTER_ARN}"

There is no additional cost to using AWS CloudShell, but if you’d like to delete your shell, refer to the Delete a shell session home directory in the AWS CloudShell User Guide.

Conclusion

Apache Kafka nearest replica fetching, or rack awareness, is a strategic cost-optimization technique. By implementing it for Amazon MSK consumers on Amazon EKS, you can significantly reduce cross-zone traffic costs while maintaining robust, distributed streaming architectures. Open source tools such as Kyverno can simplify complex configuration challenges and drive meaningful savings.The solution we’ve demonstrated provides a powerful, repeatable approach to dynamically injecting Availability Zone information into Kubernetes pods, optimize Kafka consumer routing, and minimize reduce transfer costs.

Additional resources

To learn more about rack awareness with Amazon MSK, refer to Reduce network traffic costs of your Amazon MSK consumers with rack awareness.


About the authors

Austin Groeneveld is a Streaming Specialist Solutions Architect at Amazon Web Services (AWS), based in the San Francisco Bay Area. In this role, Austin is passionate about helping customers accelerate insights from their data using the AWS platform. He is particularly fascinated by the growing role that data streaming plays in driving innovation in the data analytics space. Outside of his work at AWS, Austin enjoys watching and playing soccer, traveling, and spending quality time with his family.
Farooq Ashraf is a Senior Solutions Architect at AWS, specializing in SaaS, Generative AI, and MLOps. He is passionate about blending multi-tenant SaaS concepts with Cloud services to innovate scalable solutions for the digital enterprise, and has several blog posts, and workshops to his credit.

Near real-time baggage operational insights for airlines using Amazon Kinesis Data Streams

Post Syndicated from Subhash Sharma original https://aws.amazon.com/blogs/big-data/near-real-time-baggage-operational-insights-for-airlines-using-amazon-kinesis-data-streams/

To provide a seamless travel experience, aviation enterprises must streamline baggage handling to be as efficient as possible. Traditional baggage analytics systems often struggle with adaptability, real-time insights, data integrity, operational costs, and security, limiting their effectiveness in dynamic environments. Real-time analytics can help in several aspects, such as improving staffing decisions, baggage rerouting, payload planning, and predictive maintenance of Internet of Things (IoT) sensors and belt loaders.

In this post, we explore a framework developed by IBM to modernize baggage analytics using Amazon Web Services (AWS) managed services such as Amazon Kinesis Data Streams, Amazon DynamoDB Streams, Amazon Managed Service for Apache Flink, Amazon QuickSight, Amazon Q in QuickSight, AWS Glue, Amazon SageMaker, and Amazon Aurora within a serverless architecture. This approach delivers significant cost savings, enhanced scalability, and improved performance while providing better security and operational efficiency to meet the evolving needs of airlines. Before diving into the solution’s architecture, we first examine the traditional baggage analytics process and the need for modernization.

Importance of baggage analytics

Baggage management is a process that starts at baggage check-in and ends with the passenger claiming their baggage in a happy path scenario. The following figure explains the high-level baggage management process and respective key performance indicators (KPI). The illustration highlights the critical role of payload planning (part 1), baggage loading (part 2), and below wing payload closeout (part 3) in the flight departure process, all of which directly impact the flight on-time departure metric (part 4). Enhancing the KPIs associated with these essential steps is vital for airlines to optimize operations.

Baggage analytics KPIs

Figure 1: Baggage analytics KPIs

Common KPIs for baggage loading include baggage handling time, turnaround time impact, mishandled baggage rate, baggage accuracy rate, and baggage loading error rate. Similarly, the baggage check-in process plays a crucial role in enhancing the passenger experience. Analyzing variations in this metric across different stations and time periods provides valuable insights for identifying potential bottlenecks and improving efficiency.Airlines can measure performance KPIs using the following business process metrics:

  • Wait times – Wait times are the duration that a process step is waiting on an upstream dependency and are an important factor affecting the overall wait time. Analytics can help identify the potential areas (for example, stations, bag rooms, pier locations, belt loaders, or baggage types) where the processes and system can be fine-tuned to improve the overall wait time.
  • Error rate – Error rate is the time spent on correcting errors or defects. Within these processes, error rate is usually a result of data inconsistencies across multiple systems, manual data entries because of system unavailability or limited aircraft turn-around time, and inconsistencies between payload planning rules and loading procedures. Analytics can help classify these errors among system availability issues, outdated rules, inconsistent data between systems, and other factors. The classification can help prioritize fine-tuning and removing redundancies across systems, rules, and data.
  • Rework time – Rework time is time spent on correcting errors or defects. It can be improved but can’t be avoided, considering last-minute baggage, wheelchairs, ski equipment, and ship or aircraft changes that result in a new payload plan. Analytics can help classify the type, time, and frequency of rework activities across stations, staff members, baggage types, and scenarios related to flight delays and ship changes.
  • Cycle time – Cycle time is the time it takes to complete the process. You can improve the payload planning process cycle time by automating the payload distribution process. To do so, you need to identify and improve the time taken by the payload planning, loading, and closeout processes to reduce the complete departure process cycle time. In many cases, you can improve cycle time by adjusting the processes and adding extra resources, such as workforce, or in other cases by introducing automation. Analytics can identify these time-consuming steps and can be extended to use predictive models to apply mitigation strategies.

Traditional baggage analytics

As explained in the following figure, the traditional baggage handling solution uses monolithic databases with several upstream and downstream dependencies. Upstream dependencies include bags, flight and passenger event feeds to subscribe to the real-time changes in flight, checked bags, and passenger itinerary changes. Downstream dependencies include staffing and customer notifications. The core application interfaces include belt loaders, IoT devices, kiosks, handheld scanners, and web applications for monitoring and reporting. The airline typically stores the reports in the operational database referred to in the diagram as baggage handling (relational database), retaining historical data spanning multiple years, and makes them available to all personnel on the airline’s network. The traditional approach to baggage analytics entails nightly processing of data batches into an enterprise data warehouse (EDW) to generate performance metrics related to airlines’ baggage handling processes.

Traditional baggage analytics

Figure 2: Traditional baggage analytics

Need for modernization

Modernizing baggage analytics is crucial for airlines to achieve growth and enhance operational efficiency. Key factors influencing the modernization are as follows:

  • Inefficiencies in near real-time decision-making – Current systems can’t process and analyze data in real time, leading to delayed responses to operational issues. Integration and data silos hinder insights, preventing proactive decision-making on baggage handling, routing, and anomaly detection.
  • Limitations of traditional ETL solutions – Legacy extract, transform, and load (ETL) processes are batch-driven, slow, and resource-intensive, making them unsuitable for dynamic airline operations. High maintenance costs and frequent failures reduce system reliability and availability.
  • Challenges in proactive anomaly detection and resolution during irregular operations – Airlines struggle to anticipate baggage issues during irregular operations, such as flight delays and weather disruptions. Without predictive analytics, preemptive actions remain a challenge in optimizing staffing, reducing mishandled baggage, and enhancing operational efficiency.

Solution

The modernization of baggage operations must include breaking down the monolithic database into distinct databases based on business capabilities to address performance bottlenecks. Business capabilities can be described as fundamental abilities or competencies that a business possesses and that enable it to achieve its objectives and deliver value to its customers.

As explained in the following figure, the business capabilities for baggage management can be defined as baggage acceptance (check-in), baggage loading, baggage offloading, baggage tracking, baggage mishandling and claims, baggage rerouting, and more. [part 1]. The solution proposes Amazon DynamoDB for an operational database across all baggage management capabilities. DynamoDB global tables provide 99.999% availability with near-zero Recovery Time Objective (RTO) and Recovery Point Objective (RPO), which is crucial for mission-critical baggage handling systems. More details related to baggage operational database modernization can be found at Enhance the reliability of airlines’ mission-critical baggage handling using Amazon DynamoDB in the AWS Database Blog.

The proposed logical solution for baggage operational analytics suggests segregating operational data from historical data, referred to in the diagram as baggage analytics and historical reporting database, to enhance efficiency and alleviate the burden on the operational database [part 3].

Modern baggage analytics

Figure 3: Modern baggage analytics

The solution further uses streaming architecture for the ongoing transfer of data from the operational database to the baggage analytics and historical reporting database [part 2]. This approach aims to facilitate near real-time analytics.The key features for a robust streaming architecture include:

  • Low-latency processing to enable near real-time updates
  • Scalability and elasticity to handle dynamic workloads efficiently
  • Fault tolerance and durability to promote data reliability with replication
  • The ability for multiple consumers to process the same data in parallel at full speed without bottlenecks or interference
  • Exactly one-time processing to avoid duplication and maintain data integrity
  • Ability to replay messages

Real-time streaming on AWS Cloud

The solution uses either Kinesis Data Streams or DynamoDB Streams as a viable streaming solution for processing for change data capture (CDC) within milliseconds. For further information, refer to Streaming options for change data capture and Choose the right change data capture strategy for your Amazon DynamoDB applications.

In this architecture, Kinesis Data Streams is selected to enable fan-out to multiple downstream consumers, extended data retention, and integration with Amazon Managed Service for Apache Flink. Amazon Managed Service for Apache Flink performs stateful stream processing—such as windowed aggregation, filtering, and anomaly detection—before passing data to DynamoDB or Aurora for further analytical aggregation and reporting. Although DynamoDB Streams could also have been used, Kinesis Data Streams provides greater flexibility and throughput for the scale of event processing required here. Additionally, Kinesis Data Streams data retention allows message replays for improved reliability and analysis.

Baggage analytics on AWS Cloud

The solution will use Amazon Simple Storage Service (Amazon S3) for structured and unstructured data storage and Amazon Aurora PostgreSQL-Compatible Edition for relational aggregations. Aurora is well-suited for handling complex aggregations across multiple dimensions (such as month, year, station, and shift) with efficient indexing and SQL functions optimized for reporting. Its relational capabilities support analytical queries needed for performance metrics while providing scalability and efficiency

The following figure explains the high-level cloud architecture for baggage analytics using AWS services.

Baggage real-time analytic architecture on AWS

Figure 4: Near real-time baggage analytics architecture on AWS

The solution can support the following analytics:

  • Interactive and investigative analytics which can produce charts and graphs and discover patterns and anomalies in the baggage data used by product owners. The solution proposes using Amazon QuickSight, which is an interactive tool. Additionally, the solution proposes Amazon Q in QuickSight for natural language queries using a chat-based interface. Amazon QuickSight can be configured using an AWS Glue crawler to automatically discover and extract metadata from various data stores such as Amazon S3 and Amazon Aurora and catalog it in a centralized repository. Amazon QuickSight can be configured to use Amazon Athena to read the data catalog.
  • Predictive analytics used by data scientists involves analyzing historical data to predict future events or behaviors. It uses statistical algorithms and machine learning (ML) techniques to forecast outcomes. The proposed solution is to use a SageMaker notebook to perform predictive analytics on baggage data.

Conclusion

Cloud-based solutions such as Kinesis Data Streams, Athena, and QuickSight revolutionize baggage analytics with scalable, cost-effective infrastructure. By integrating real-time data streaming, analysis, and visualization, they eliminate data silos and enable data-driven decision-making.This modernization optimizes processes, proactively resolving issues to minimize passenger disruptions. Embracing cloud-powered analytics isn’t just a necessity but a strategic step toward greater efficiency, resilience, and customer satisfaction.With this solution, airlines can enhance preemptive issue resolution in baggage operations. Real-time analytics enables better workforce planning, allowing airlines to predict staffing needs at departure and arrival stations, reducing labor costs while ensuring smooth operations. Additionally, data-driven insights help identify inefficiencies during irregular operations, enabling informed decisions for traffic diversion and process optimization.

Check out more AWS Partners or contact an AWS Representative to know how we can help accelerate your business.

Further reading

IBM Consulting is an AWS Premier Tier Services Partner that helps customers who use AWS to harness the power of innovation and drive their business transformation. They are recognized as a Global Systems Integrator (GSI) for over 22 competencies, including travel and hospitality consulting. For more information, please contact an IBM Representative.


About the authors

Neeraj Kaushik is an Open Group Certified Distinguish Architect at IBM with two decades of experience in client-facing delivery roles. His experience spans several industries, including travel and transportation, banking, retail, education, healthcare, and anti-human trafficking. As a trusted advisor, he works directly with the client executive and architects on business strategy to define a technology roadmap. As a hands-on Chief Architect AWS Professional Certified Solution Architect, AWS Certified Machine Learning Specialist and Natural Language Processing Expert, he has led multiple complex cloud modernization programs and AI initiatives.

Jay Pandya is a Senior Partner Solutions Architect in the Global Systems Integrator (GSI) team at Amazon Web Services (AWS). He has over 30 years of IT experience and is helping and providing guidance to AWS GSI partners to build, design, and architect agile, scalable, highly available, and secure solutions on AWS. Outside of the office, Jay enjoys spending time with his family and traveling, and he is an aviation enthusiast and avid sports and Formula 1 fan.

Vijay Gokarn is a Senior Solution Architect at IBM with extensive experience across industries including financial services, healthcare, industrial, retail, and travel and hospitality. He leads complex AWS transformation initiatives, drawing on his hands-on expertise as an AWS Certified Solutions Architect Associate. Vijay specializes in serverless architectures, event-driven systems, and enterprise modernization. As a skilled architect and team leader, he has delivered impactful solutions in cloud modernization, digital banking, and intelligent automation. His passion lies in bridging business strategy with technical execution to drive scalable digital transformation.

Subhash Sharma is Sr. Partner Solutions Architect at AWS. He has more than 25 years of experience in delivering distributed, scalable, highly available, and secured software products using Microservices, AI/ML, the Internet of Things (IoT), and Blockchain using a DevSecOps approach. In his spare time, Subhash likes to spend time with family and friends, hike, walk on beach, and watch TV.

Overcome your Kafka Connect challenges with Amazon Data Firehose

Post Syndicated from Swapna Bandla original https://aws.amazon.com/blogs/big-data/overcome-your-kafka-connect-challenges-with-amazon-data-firehose/

Apache Kafka is a popular open source distributed streaming platform that is widely used in the AWS ecosystem. It’s designed to handle real-time, high-throughput data streams, making it well-suited for building real-time data pipelines to meet the streaming needs of modern cloud-based applications.

For AWS customers looking to run Apache Kafka, but don’t want to worry about the undifferentiated heavy lifting involved with self-managing their Kafka clusters, Amazon Managed Streaming for Apache Kafka (Amazon MSK) offers fully managed Apache Kafka. This means Amazon MSK provisions your servers, configures your Kafka clusters, replaces servers when they fail, orchestrates server patches and upgrades, makes sure clusters are architected for high availability, makes sure data is durably stored and secured, sets up monitoring and alarms, and runs scaling to support load changes. With a managed service, you can spend your time developing and running streaming event applications.

For applications to use data sent to Kafka, you need to write, deploy, and manage application code that consumes data from Kafka.

Kafka Connect is an open-source component of the Kafka project that provides a framework for connecting with external systems such as databases, key-value stores, search indexes, and file systems from your Kafka clusters. On AWS, our customers commonly write and manage connectors using the Kafka Connect framework to move data out of their Kafka clusters into persistent storage, like Amazon Simple Storage Service (Amazon S3), for long-term storage and historical analysis.

At scale, customers need to programmatically manage their Kafka Connect infrastructure for consistent deployments when updates are required, as well as the code for error handling, retries, compression, or data transformation as it is delivered from your Kafka cluster. However, this introduces a need for investment into the software development lifecycle (SDLC) of this management software. Although the SDLC is a cost-effective and time-efficient process to help development teams build high-quality software, for many customers, this process is not desirable for their data delivery use case, particularly when they could dedicate more resources towards innovating for other key business differentiators. Beyond SDLC challenges, many customers face fluctuating data streaming throughput. For instance:

  • Online gaming businesses experience throughput variations based on game usage
  • Video streaming applications see changes in throughput depending on viewership
  • Traditional businesses have throughput fluctuations tied to consumer activity

Striking the right balance between resources and workload can be challenging. Under-provisioning can lead to consumer lag, processing delays, and potential data loss during peak loads, hampering real-time data flows and business operations. On the other hand, over-provisioning results in underutilized resources and unnecessary high costs, making the setup economically inefficient for customers. Even the action of scaling up your infrastructure introduces additional delays because resources need to be provisioned and acquired for your Kafka Connect cluster.

Even when you can estimate aggregated throughput, predicting throughput per individual stream remains difficult. As a result, to achieve smooth operations, you might resort to over-provisioning your Kafka Connect resources (CPU) for your streams. This approach, though functional, might not be the most efficient or cost-effective solution.

Customers have been asking for a fully serverless solution that will not only handle managing resource allocation, but transition the cost model to only pay for the data they are delivering from the Kafka topic, instead of underlying resources that require constant monitoring and management.

In September 2023, we announced a new integration between Amazon and Amazon Data Firehose, allowing builders to deliver data from their MSK topics to their destination sinks with a fully managed, serverless solution. With this new integration, you no longer needed to develop and manage your own code to read, transform, and write your data to your sink using Kafka Connect. Data Firehose abstracts away the retry logic required when reading data from your MSK cluster and delivering it to the desired sink, as well as infrastructure provisioning, because it can scale out and scale in automatically to adjust to the volume of data to transfer. There are no provisioning or maintenance operations required on your side.

At release, the checkpoint time to start consuming data from the MSK topic was the creation time of the Firehose stream. Data Firehose couldn’t start reading from other points on the data stream. This caused challenges for several different use cases.

For customers that are setting up a mechanism to sink data from their cluster for the first time, all data in the topic older than the timestamp of Firehose stream creation would need another way to be persisted. For example, customers using Kafka Connect connectors, like These users were limited in using Data Firehose because they wanted to sink all the data from the topic to their sink, but Data Firehose couldn’t read data from earlier than the timestamp of Firehose stream creation.

For other customers that were running Kafka Connect and needed to migrate from their Kafka Connect infrastructure to Data Firehose, this required some extra coordination. The release functionality of Data Firehose means you can’t point your Firehose stream to a specific point on the source topic, so a migration requires stopping data ingest to the source MSK topic and waiting for Kafka Connect to sink all the data to the destination. Then you can create the Firehose stream and restart the producers such that the Firehose stream can then consume new messages from the topic. This adds additional, and non-trivial, overhead to the migration effort when attempting to cut over from an existing Kafka Connect infrastructure to a new Firehose stream.

To address these challenges, we’re happy to announce a new feature in the Data Firehose integration with Amazon MSK. You can now specify the Firehose stream to either read from the earliest position on the Kafka topic or from a custom timestamp to begin reading from your MSK topic.

In the first post of this series, we focused on managed data delivery from Kafka to your data lake. In this post, we extend the solution to choose a custom timestamp for your MSK topic to be synced to Amazon S3.

Overview of Data Firehose integration with Amazon MSK

Data Firehose integrates with Amazon MSK to offer a fully managed solution that simplifies the processing and delivery of streaming data from Kafka clusters into data lakes stored on Amazon S3. With just a few clicks, you can continuously load data from your desired Kafka clusters to an S3 bucket in the same account, eliminating the need to develop or run your own connector applications. The following are some of the key benefits to this approach:

  • Fully managed service – Data Firehose is a fully managed service that handles the provisioning, scaling, and operational tasks, allowing you to focus on configuring the data delivery pipeline.
  • Simplified configuration – With Data Firehose, you can set up the data delivery pipeline from Amazon MSK to your sink with just a few clicks on the AWS Management Console.
  • Automatic scaling – Data Firehose automatically scales to match the throughput of your Amazon MSK data, without the need for ongoing administration.
  • Data transformation and optimization – Data Firehose offers features like JSON to Parquet/ORC conversion and batch aggregation to optimize the delivered file size, simplifying data analytical processing workflows.
  • Error handling and retries – Data Firehose automatically retries data delivery in case of failures, with configurable retry durations and backup options.
  • Offset select option – With Data Firehose, you can select the starting position for the MSK delivery stream to be delivered within a topic from three options:
    • Firehose stream creation time – This allows you to deliver data starting from Firehose stream creation time. When migrating from to Data Firehose, if you have an option to pause the producer, you can consider this option.
    • Earliest – This allows you to deliver data starting from MSK topic creation time. You can choose this option if you’re setting a new delivery pipeline with Data Firehose from Amazon MSK to Amazon S3.
    • At timestamp – This option allows you to provide a specific start date and time in the topic from where you want the Firehose stream to read data. The time is in your local time zone. You can choose this option if you prefer not to stop your producer applications while migrating from Kafka Connect to Data Firehose. You can refer to the Python script and steps provided later in this post to derive the timestamp for the latest events in your topic that were consumed by Kafka Connect.

The following are benefits of the new timestamp selection feature with Data Firehose:

  • You can select the starting position of the MSK topic, not just from the point that the Firehose stream is created, but from any point from the earliest timestamp of the topic.
  • You can replay the MSK stream delivery if required, for example in the case of testing scenarios to select from different timestamps with the option to select from a specific timestamp.
  • When migrating from Kafka Connect to Data Firehose, gaps or duplicates can be managed by selecting the starting timestamp for Data Firehose delivery from the point where Kafka Connect delivery ended. Because the new custom timestamp feature isn’t monitoring Kafka consumer offsets per partition, the timestamp you select for your Kafka topic should be a few minutes before the timestamp at which you stopped Kafka Connect. The earlier the timestamp you select, the more duplicate records you will have downstream. The closer the timestamp to the time of Kafka Connect stopping, the higher the likelihood of data loss if certain partitions have fallen behind. Be sure to select a timestamp appropriate to your requirements.

Overview of solution

We discuss two scenarios to stream data.

In Scenario 1, we migrate to Data Firehose from Kafka Connect with the following steps:

  1. Derive the latest timestamp from MSK events that Kafka Connect delivered to Amazon S3.
  2. Create a Firehose delivery stream with Amazon MSK as the source and Amazon S3 as the destination with the topic starting position as Earliest.
  3. Query Amazon S3 to validate the data loaded.

In Scenario 2, we create a new data pipeline from Amazon MSK to Amazon S3 with Data Firehose:

  1. Create a Firehose delivery stream with Amazon MSK as the source and Amazon S3 as the destination with the topic starting position as At timestamp.
  2. Query Amazon S3 to validate the data loaded.

The solution architecture is depicted in the following diagram.

Prerequisites

You should have the following prerequisites:

  • An AWS account and access to the following AWS services:
  • An MSK provisioned or MSK serverless cluster with topics created and data streaming to it. The sample topic used in this is order.
  • An EC2 instance configured to use as a Kafka admin client. Refer to Create an IAM role for instructions to create the client machine and IAM role that you will need to run commands against your MSK cluster.
  • An S3 bucket for delivering data from Amazon MSK using Data Firehose.
  • Kafka Connect to deliver data from Amazon MSK to Amazon S3 if you want to migrate from Kafka Connect (Scenario 1).

Migrate to Data Firehose from Kafka Connect

To reduce duplicates and minimize data loss, you need to configure your custom timestamp for Data Firehose to read events as close to the timestamp of the oldest committed offset that Kafka Connect reported. You can follow the steps in this section to visualize how the timestamps of each committed offset will vary by partition across the topic you want to read from. This is for demonstration purposes and doesn’t scale as a solution for workloads with a large number of partitions.

Sample data was generated for demonstration purposes by following the instructions referenced in the following GitHub repo. We set up a sample producer application that generates clickstream events to simulate users browsing and performing actions on an imaginary ecommerce website.

To derive the latest timestamp from MSK events that Kafka Connect delivered to Amazon S3, complete the following steps:

  1. From your Kafka client, query Amazon MSK to retrieve the Kafka Connect consumer group ID:
    ./kafka-consumer-groups.sh --bootstrap-server $bs --list --command-config client.properties

  2. Stop Kafka Connect.
  3. Query Amazon MSK for the latest offset and associated timestamp for the consumer group belonging to Kafka Connect.

You can use the get_latest_offsets.py Python script from the following GitHub repo as a reference to get the timestamp associated with the latest offsets for your Kafka Connect consumer group. To enable authentication and authorization for a non-Java client with an IAM authenticated MSK cluster, refer to the following GitHub repo for instructions on installing the aws-msk-iam-sasl-signer-python package for your client.

python3 get_latest_offsets.py --broker-list $bs --topic-name “order” --consumer-group-id “connect-msk-serverless-connector-090224” --aws-region “eu-west-1”

Note the earliest timestamp across all the partitions.

Create a data pipeline from Amazon MSK to Amazon S3 with Data Firehose

The steps in this section are applicable to both scenarios. Complete the following steps to create your data pipeline:

  1. On the Data Firehose console, choose Firehose streams in the navigation pane.
  2. Choose Create Firehose stream.
  3. For Source, choose Amazon MSK.
  4. For Destination, choose Amazon S3.
  5. For Source settings, browse to the MSK cluster and enter the topic name you created as part of the prerequisites.
  6. Configure the Firehose stream starting position based on your scenario:
    1. For Scenario 1, set Topic starting position as At Timestamp and enter the timestamp you noted in the previous section.
    2. For Scenario 2, set Topic starting position as Earliest.
  7. For Firehose stream name, leave the default generated name or enter a name of your preference.
  8. For Destination settings, browse to the S3 bucket created as part of the prerequisites to stream data.

Within this S3 bucket, by default, a folder structure with YYYY/MM/dd/HH will be automatically created. Data will be delivered to subfolders pertaining to the HH subfolder according to the Data Firehose to Amazon S3 ingestion timestamp.

  1. Under Advanced settings, you can choose to create the default IAM role for all the permissions that Data Firehose needs or choose existing an IAM role that has the policies that Data Firehose needs.
  2. Choose Create Firehose stream.

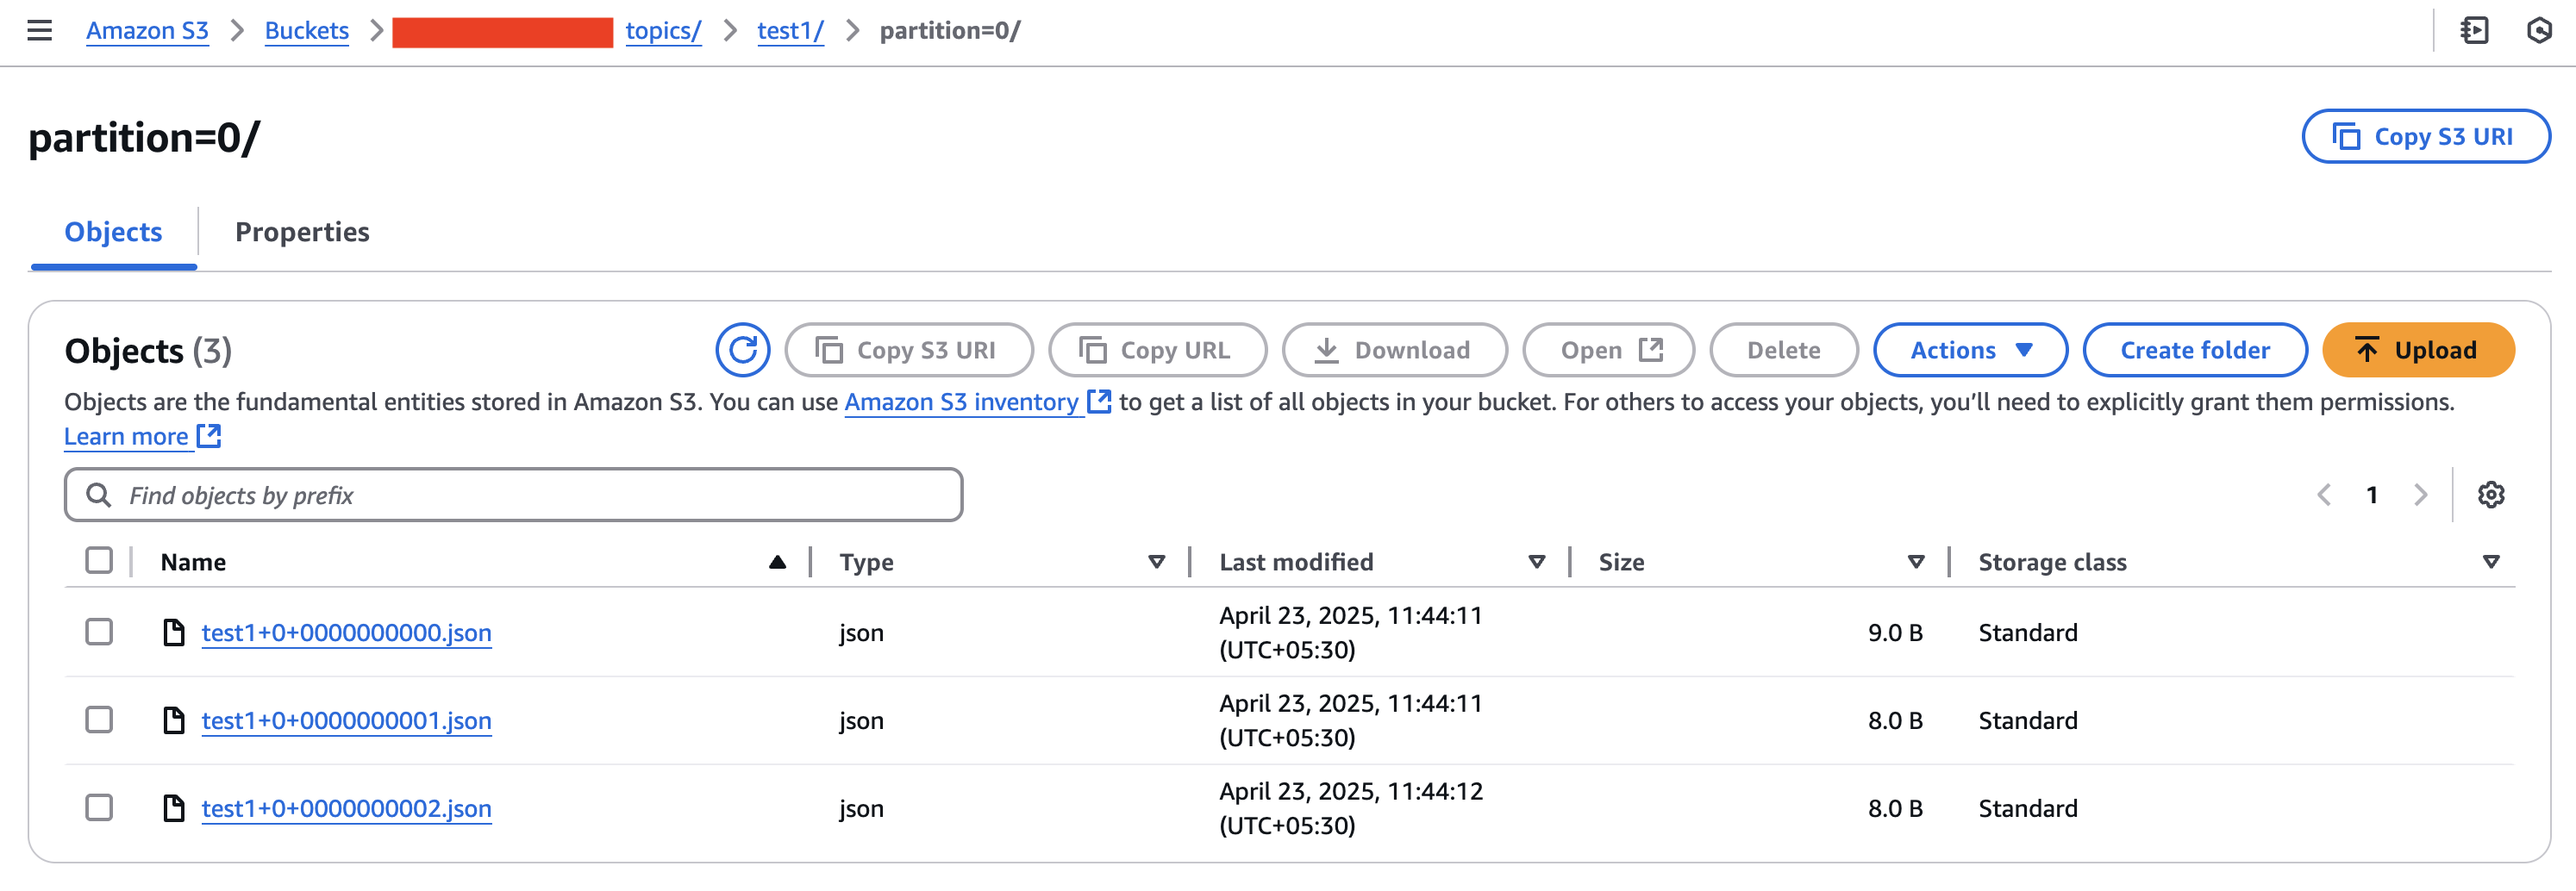
On the Amazon S3 console, you can verify the data streamed to the S3 folder according to your chosen offset settings.

Clean up

To avoid incurring future charges, delete the resources you created as part of this exercise if you’re not planning to use them further.

Conclusion

Data Firehose provides a straightforward way to deliver data from Amazon MSK to Amazon S3, enabling you to save costs and reduce latency to seconds. To try Data Firehose with Amazon S3, refer to the Delivery to Amazon S3 using Amazon Data Firehose lab.


About the Authors

Swapna Bandla is a Senior Solutions Architect in the AWS Analytics Specialist SA Team. Swapna has a passion towards understanding customers data and analytics needs and empowering them to develop cloud-based well-architected solutions. Outside of work, she enjoys spending time with her family.

Austin Groeneveld is a Streaming Specialist Solutions Architect at Amazon Web Services (AWS), based in the San Francisco Bay Area. In this role, Austin is passionate about helping customers accelerate insights from their data using the AWS platform. He is particularly fascinated by the growing role that data streaming plays in driving innovation in the data analytics space. Outside of his work at AWS, Austin enjoys watching and playing soccer, traveling, and spending quality time with his family.

Building serverless event streaming applications with Amazon MSK and AWS Lambda

Post Syndicated from Tarun Rai Madan original https://aws.amazon.com/blogs/big-data/building-serverless-event-streaming-applications-with-amazon-msk-and-aws-lambda/

As organizations build modern applications with event-driven architectures (EDA), they often seek solutions that minimize infrastructure management overhead while maximizing developer productivity. Amazon Managed Streaming for Apache Kafka (Amazon MSK) and AWS Lambda together provide a serverless, scalable, and cost-efficient platform for real-time event-driven processing.

In this post, we describe how you can simplify your event-driven application architecture using AWS Lambda with Amazon MSK. We demonstrate how to configure Lambda as a consumer for Kafka topics, including a cross-account setup and how to optimize price and performance for these applications.

Why use Lambda with Amazon MSK?

Customers building event-driven applications have several key priorities when it comes to their architecture choices. They typically seek to reduce their operational overhead by using Amazon Web Services (AWS) to handle the complex, underlying infrastructure components so their teams can focus on core business logic. Additionally, developers prefer a streamlined experience that minimizes the need for repetitive boilerplate code, enabling them to be more productive and focus on creating value. Furthermore, these customers want to achieve both scalability and cost-effectiveness without the burden of managing compute infrastructure directly. Lambda integration with Amazon MSK effectively addresses these requirements, delivering a comprehensive solution that combines the benefits of serverless computing with managed Kafka services. For example, an ecommerce company can use Amazon MSK to collect real-time clickstream data from its website and process those events using AWS Lambda. With this integration, they can trigger Lambda functions to update recommendation models, send personalized offers, or analyze user behavior instantly—without provisioning or managing servers. The key benefits of using Lambda with Amazon MSK include:

  1. Simplicity through native integration – AWS Lambda offers native integration with Amazon MSK through a connector resource called event source mapping. You can use this integration to directly associate a Kafka topic—whether it’s on Amazon MSK or a self-managed Kafka cluster—as an event source for a Lambda function without writing custom consumer logic. With just a few configuration steps, event source mapping handles partition assignment, offset tracking, and parallelized batch processing under the hood. It uses the Kafka consumer group protocol to distribute topic partitions across multiple concurrent Lambda invocations, supports batch windowing, and enables at-least-once delivery semantics. Moreover, it automatically commits offsets upon successful function execution while handling retries and dead-letter queue (DLQ) routing for failed records, significantly reducing the operational overhead traditionally associated with Kafka consumers.
  2. Auto scaling and throughput controls – When using AWS Lambda with Amazon MSK through event source mapping, Lambda automatically scales by assigning a dedicated event poller per Kafka partition, enabling parallel, partition-based processing. This allows the system to elastically handle varying traffic without manual intervention. For advanced control, provisioned concurrency pre-initializes Lambda execution environments, eliminating cold starts and delivering consistent low-latency performance. Additionally, with provisioned event source mapping, you can configure the minimum and maximum number of Kafka pollers, providing precise control over throughput and concurrency. This is ideal for applications with unpredictable traffic patterns or strict latency requirements.
  3. Cost-effectiveness – AWS Lambda uses a pay-per-use model in which you only pay for compute time and number of invocations. When integrated with Amazon MSK, there are no charges for idle time, making it ideal for bursty or low-frequency Kafka workloads. You can further optimize costs by tuning batch size and batch window settings. For mission-critical workloads, provisioned concurrency provides consistent performance with controlled pricing.
  4. Event filtering – AWS Lambda supports event filtering for Amazon MSK event sources, which means you can process only the Kafka records that match specific criteria. This reduces unnecessary function invocations and optimizes your function costs. You can define up to five filters per event source mapping (with the option to request an increase to ten). Each filter uses a JSON-based pattern to specify the conditions a record must meet to be processed. Filters can be applied using the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS Serverless Application Model (AWS SAM) templates. For more details and examples, refer to the AWS Lambda documentation on event filtering with Amazon MSK.
  5. Handling Availability Zone outage for your consumer – Amazon MSK enables high availability for your Kafka brokers by distributing them across multiple Availability Zones within a Region. To maintain high availability across your application, you similarly need a consumer that offers high availability. AWS Lambda offers high availability and resilience by running your consumer functions across multiple Availability Zones in a Region. This means that even if one Availability Zone experiences an outage, your Lambda function will continue to operate in other healthy Availability Zones. While Lambda manages security patching and Availability Zone failure scenarios, you can focus on your application logic.
  6. Cross-account event processingCross-account connectivity between AWS Lambda and Amazon MSK allows a Lambda function in one AWS account to consume data from an MSK cluster in another account using MSK multi-VPC private connectivity powered by AWS PrivateLink. This setup is particularly beneficial for organizations that centralize Kafka infrastructure while maintaining separate accounts for different applications or teams.
  7. Support for JSON, Avro, Protobuf, and Schema Registries – AWS Lambda supports Kafka events in JSON, Avro and Protobuf formats via event source mapping. It integrates with AWS Glue Schema registry, Confluent Cloud Schema registry, and self-managed Confluent Schema registry , enabling native schema validation, filtering, and deserialization without custom code.

How Lambda processes messages from your Kafka topic

Lambda uses event source mappings to process records from Amazon MSK by actively polling Kafka topics through event pollers that invoke Lambda functions with batches of records. These mappings are Lambda managed resources designed for high-throughput, stream-based processing. By default, Lambda detects the OffsetLag for all partitions in your Kafka topic and automatically scales pollers based on traffic. For high-throughput applications, you can enable provisioned mode to define minimum and maximum pollers, and your event source mapping auto scales between the minimum and maximum defined values. In the provisioned mode, each poller can process up to 5 MBps and supports concurrent Lambda invocations.

After Lambda processes each batch, it commits the offsets of the messages in that batch. If your function returns an error for a message in a batch, Lambda retries the whole batch of messages until processing succeeds or the messages expire. You can send records that fail all retry attempts to an on-failure destination for later processing. To maintain ordered processing within a partition, Lambda limits the maximum event pollers to the number of partitions in the topic. When setting up Kafka as a Lambda event source, you can specify a consumer group ID to let Lambda join an existing Kafka consumer group. If other consumers are active in that group, Lambda will receive only part of the topic’s messages. If the group exists, Lambda starts from the group’s committed offset, ignoring the StartingPosition. The following diagram illustrates this flow.

Walkthrough: Build a serverless Kafka app with AWS Lambda

Follow these steps to build a serverless application that consumes messages from an MSK cluster using AWS Lambda:

  1. Create an Amazon MSK cluster. Use the AWS Management Console or AWS CLI to create your MSK cluster. When the cluster is up, create your Kafka topic(s). For detailed instructions, refer to the Amazon MSK documentation.
  2. Create a Lambda function using the AWS Management Console or the AWS CLI. To learn more about creating a Lambda function, refer to Create your first Lambda function. The Lambda function’s execution role needs to have the following permissions:
    1. Access to connect to your MSK cluster
    2. Permissions to manage elastic network interfaces in your VPC
  3. To connect Lambda to Amazon MSK as a consumer, set up event source mapping to link your MSK topic with the Lambda function. This allows Lambda to automatically poll for new messages and process them. Follow the guide on how to configure event source mapping.

For reference, configuring event source mapping involves three steps:

  1. Network setup – In the default event source mapping mode, you need to configure a networking setup using a PrivateLink endpoint or NAT gateway for event source mapping to invoke Lambda functions. In provisioned mode, no networking configuration is needed (and you don’t incur the cost of networking components).
  2. Event source mapping parameter configuration – This involves setting necessary configuration parameters for the event source mapping to be able to poll messages from your Kafka cluster. This includes the MSK cluster, topic name, consumer group ID, authentication method, and optionally, schema registry, scaling mode. You can configure the scaling mode for provisioned throughput, along with batch size, batch window, and event filtering for your event source mapping.
  3. Access permissions – This involves configuring required permissions to access the required AWS resources, and includes configuring permissions for the function to execute the code, permissions for the event source mapping to access your MSK cluster, and permissions for Lambda to access your VPC resources.

The following screenshot shows the console setup for configuring Amazon MSK event source mapping, including the Amazon MSK trigger related fields.

The following screenshot shows event poller configuration.

The following screenshot shows additional settings you can use, depending on your use case.

Optimizing AWS Lambda for stream processing with Amazon MSK

When building real-time data processing pipelines with Amazon MSK and AWS Lambda, it’s important to tune your setup for both performance and cost-efficiency. Lambda offers powerful serverless compute capabilities, but to get the most out of it in a streaming context, you need to make a few key optimizations:

  1. Enable provisioned concurrency for low-latency processing – For workloads that are sensitive to latency—cold starts can introduce unwanted delays. By enabling provisioned concurrency, you can pre-warm a specified number of Lambda instances so they’re always ready to handle traffic immediately. This eliminates cold starts and provides consistent response times, which is crucial for latency-critical use cases.
  2. Enable provisioned mode for event source mapping for high-throughput processing – For Kafka workloads with stringent throughput requirements, activate the provisioned mode. The optimal configuration of minimum and maximum event pollers for your Kafka event source mapping depends on your application’s performance requirements. Start with the default minimum event pollers to baseline the performance profile and adjust event pollers based on observed message processing patterns and your application’s performance requirements. For workloads with spiky traffic and strict performance needs, increase the minimum event pollers to handle sudden surges. You can fine-tune the minimum event pollers by evaluating your desired throughput, your observed throughput, which depends on factors such as the ingested messages per second and average payload size, and using the throughput capacity of one event poller (up to 5 MB/s) as reference. To maintain ordered processing within a partition, Lambda caps the maximum event pollers at the number of partitions in the topic.
  3. Optimize message batching using size and windowing – By integrating Lambda with Amazon MSK, you can control how messages are batched before they’re sent to your function. Tuning parameters such as batch size (the number of records per invocation: 1–10,000 records) and maximum batching window (how long to wait for a full batch: 0–300 seconds) can significantly impact performance. Larger batches mean fewer invocations, which reduces overhead and improves throughput. However, it’s important to strike a balance—too large a batch or window might introduce unwanted processing delays. Monitor your stream’s behavior and adjust these settings based on throughput requirements and acceptable latency.
  4. Apply filters to reduce unnecessary invocations – Not every record in your Kafka topic might require processing. To avoid unnecessary Lambda invocations (and associated costs), apply filtering logic directly when configuring the event source mapping. With Lambda, you can define filtering (up to 10 filters) criteria so that only relevant records trigger your function. This helps reduce compute time, minimize noise, and optimize your budget, especially when dealing with high-throughput topics with mixed content. For Amazon MSK, Lambda commits offsets for matched and unmatched messages after successfully invoking the function.

Conclusion

By combining Amazon MSK with AWS Lambda, you can seamlessly build modern, serverless event-driven applications. This integration eliminates the need to manage consumer groups, compute infrastructure, or scaling logic so teams can focus on delivering business value faster.

Whether you’re integrating Kafka into microservices, transforming data pipelines, or building reactive applications, Lambda with Amazon MSK is a powerful and flexible serverless solution. For detailed documentation on how to configure Lambda with Amazon MSK, refer to the AWS Lambda Developer Guide. For more serverless learning resources, visit Serverless Land.


About the Authors

Tarun Rai Madan is a Principal Product Manager at Amazon Web Services (AWS). He specializes in serverless technologies and leads product strategy to help customers achieve accelerated business outcomes with event-driven applications, using services like AWS Lambda, AWS Step Functions, Apache Kafka, and Amazon SQS/SNS. Prior to AWS, he was an engineering leader in the semiconductor industry, and led development of high-performance processors for wireless, automotive, and data center applications.

Masudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.

Introducing AWS Lambda native support for Avro and Protobuf formatted Apache Kafka events

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/introducing-aws-lambda-native-support-for-avro-and-protobuf-formatted-apache-kafka-events/

AWS Lambda now provides native support for Apache Avro and Protocol Buffers (Protobuf) formatted events with Apache Kafka event source mapping (ESM) when using Provisioned Mode. The support allows you to validate your schema with popular schema registries. This allows you to use and filter the more efficient binary event formats and share data using schema in a centralized and consistent way. This blog post shows how you can use Lambda to process Avro and Protobuf formatted events from Kafka topics using schema registry integration.

This new capability works with both Amazon Managed Streaming for Apache Kafka (Amazon MSK), Confluent Cloud and self-managed Kafka clusters. To get started, update your existing Kafka ESM to Provisioned Mode and add schema registry configuration, or create a new ESM in Provisioned Mode with schema registry integration enabled.

Avro and Protobuf

Many organizations use Avro and Protobuf formats with Apache Kafka because these binary serialization formats offer advantages over JSON. They provide 50-80% smaller message sizes, faster serialization and deserialization performance, robust schema evolution capabilities, and strong typing across multiple programming languages.Working with these formats in Lambda functions previously necessitated custom code. Developers needed to implement schema registry clients, handle authentication and caching, write format-specific deserialization logic, and manage schema evolution scenarios.

What’s new

Lambda’s Kafka Event Source Mapping (ESM) now provides built-in integration with AWS Glue Schema Registry, Confluent Cloud Schema Registry, and self-managed Confluent Schema Registry. When you configure schema registry settings for your Kafka ESM, the service automatically validates incoming JSON Schema, Avro, and Protobuf records against their registered schema. This moves complex schema registry integration logic from your application layer to the managed Lambda service.

You can build your function with Kafka’s open-source ConsumerRecords interface using Powertools for AWS Lambda to get your Avro or Protobuf generated business objects directly. Optionally you can specify to get your records in the JSON format, where your function receives clean, validated JSON data regardless of the original serialization format, removing the need for custom deserialization code in your Lambda functions. This also allows you to create Kafka consumers across multiple programming languages.

Powertools for AWS Lambda is a developer toolkit that provides specific support for Java, .NET, Python, and TypeScript, maintaining consistency with existing Kafka development patterns. You can directly access business objects without custom deserialization code.

You can also setup filtering rules to discard irrelevant, JSON, Avro or Protobuf formatted events before function invocations, which can improve processing performance and reduce costs.

How schema validation works

When you configure schema registry integration for your Kafka ESM, you specify the registry endpoint, authentication details, and which event fields (key, value, or both) to validate. The ESM polls your Kafka topics for records as usual but now performs additional processing before invoking your Lambda function.For each incoming event, the ESM extracts the schema ID embedded in the serialized data. It fetches the corresponding schema from your configured registry. This process happens transparently, with schema definitions cached for up to 24 hours to optimize performance. The ESM identifies the format of your events using schema metadata and validates the event structure. It keeps either the original binary data or deserializes it to JSON format based on your customer configuration and sends it to your function for processing.


Figure 1: Kafka processing flow diagram.

The ESM handles schema evolution automatically. When producers begin using new schema versions, the service detects the updated schema IDs and fetches the latest definitions from your registry. This makes sure that your functions always receive properly deserialized data without requiring code changes.

Event record format

As a part of the ESM schema registry configuration, you need to specify Event Record Format, which Lambda uses to deliver validated records to your function. The schema registry configuration supports SOURCE and JSON.

SOURCE preserves the original binary format of the data as a base64-encoded string with producer-appended schema-id removed. This allows direct conversion to Avro or Protobuf objects so that you can use Kafka’s ConsumerRecords interface for a Kafka-like experience. Use this format when working with strongly typed languages or when you need to maintain the full capabilities of Avro or Protobuf schemas. Then, you can use any Avro or Protobuf deserializer to convert raw bytes to your business object. Powertools provides native support for this deserialization.

With JSON, the ESM deserializes the data ready for direct use in languages with native JSON support. Use this when you don’t need to preserve the original binary format or work with generated classes. You can also use Powertools to convert the base64 to your business object. See the documentation for payload formats and deserialization behavior.

If you configure filtering rules, then they operate on the JSON-formatted events after deserialization. This upstream filtering prevents unnecessary Lambda invocations for events that don’t match your processing criteria, directly reducing your compute costs.

Configuration and setup

To use this feature, you must enable Provisioned Mode for your Kafka ESM, which provides the dedicated compute resources needed for schema registry integration.

You can configure the integration through the AWS Management ConsoleAWS Command Line Interface (AWS CLI)AWS Language SDKs, or infrastructure as code (IaC) tools such as the AWS Serverless Application Model (AWS SAM) or AWS Cloud Development Kit (AWS CDK).

Your schema registry configuration includes the registry endpoint URL, authentication method (AWS Identity and Access Management (IAM) for AWS Glue Schema Registry, or Basic Auth, SASL/SCRAM, or mTLS for Confluent registries), and validation settings. You specify which event attributes to validate and optionally define filtering rules using standard Lambda event filtering syntax.

For error handling, configure Lambda failure destinations where events that fail schema validation or deserialization are sent. This makes sure that problematic events don’t disappear silently but are routed to other services such as Amazon Simple Queue Service (Amazon SQS), Amazon Simple Notification Service (Amazon SNS), and Amazon S3 for debugging and analysis.

Seeing the new features in action

There are a number of Serverless Patterns that you can use to process Kafka streams using Lambda. This example uses the Java pattern.

Deploy a sample Amazon MSK cluster

To set up an Amazon MSK cluster, follow the instructions in the GitHub repo and create a new AWS CloudFormation stack using the MSKAndKafkaClientEC2.yaml template file. The stack creates the Amazon MSK cluster, along with a client Amazon EC2 instance, to manage the Kafka cluster. There are costs involved when running this infrastructure.

  1. Connect to the EC2 instance using EC2 Instance Connect.
  2. Check that the Kafka topic is created by checking the contents of the kafka_topic_creator_output.txt file.
    cat kafka_topic_creator_output.txt

  3. The file should contain the text: “Created topic MskIamJavaLambdaTopic.”

Deploy the Glue schema registry and consumer Lambda function

The EC2 instance contains the software needed to deploy the schema registry and Lambda function.

  1. Change directory to the pattern directory.
    cd serverless-patterns/msk-lambda-iam-java-sam
  2. Build the application using AWS SAM.
    sam build
  3. To deploy your application for the first time, run the following in the EC2 instance shell:
    sam deploy --capabilities CAPABILITY_IAM --no-confirm-changeset \
    	--no-disable-rollback --region $AWS_REGION --stack-name msk-lambda-schema-avro-java-sam --guided

  4. You can accept all the defaults by hitting Enter. You can browse to the AWS Glue schema registry console and view the ContactSchema definition:
    {
      "type": "record",
      "name": "Contact",
      "fields": [
        {"name": "firstname", "type": "string"},
        {"name": "lastname", "type": "string"},
        {"name": "company", "type": "string"},
        {"name": "street", "type": "string"},
        {"name": "city", "type": "string"},
        {"name": "county", "type": "string"},
        {"name": "state", "type": "string"},
        {"name": "zip", "type": "string"},
        {"name": "homePhone", "type": "string"},
        {"name": "cellPhone", "type": "string"},
        {"name": "email", "type": "string"},
        {"name": "website", "type": "string"}
      ]
    }
    

    The consumer Lambda function ESM is configured for Provisioned Mode.

  5. View the ESM configuration from the Lambda console for the Lambda function name prefixed with msk-lambda-schema-avro-ja-LambdaMSKConsumer.
  6. Choose the MSK Lambda trigger which opens the Triggers pane under Configuration.
    Figure 2: View Lambda ESM schema configuration
  7. The configuration specifies using the Event record format SOURCE so your function can use Kafka’s native open-source ConsumerRecords interface. Powertools then deserializes the payload.
  8. The schema validation attribute is VALUE.
  9. The ESM filter configuration only processes the records that match zip codes of 2000.
  10. In your function code, specify the open-source Kafka ConsumersRecords interface by including Powertools for Lambda as a dependency. ConsumerRecords provides metadata about Kafka records and allows you to get direct access to your Avro/Protobuf generated business objects without requiring any additional deserialization code.
package com.amazonaws.services.lambda.samples.events.msk;

import com.amazonaws.services.lambda.runtime.Context;
import com.amazonaws.services.lambda.runtime.RequestHandler;
import org.apache.kafka.clients.consumer.ConsumerRecord;
import org.apache.kafka.clients.consumer.ConsumerRecords;
import org.slf4j.Logger;
import org.slf4j.LoggerFactory;
import software.amazon.lambda.powertools.kafka.Deserialization;
import software.amazon.lambda.powertools.kafka.DeserializationType;
import software.amazon.lambda.powertools.logging.Logging;

public class AvroKafkaHandler implements RequestHandler<ConsumerRecords<String, Contact>, String> {
    private static final Logger LOGGER = LoggerFactory.getLogger(AvroKafkaHandler.class);

    @Override
    @Logging(logEvent = true)
    @Deserialization(type = DeserializationType.KAFKA_AVRO)
    public String handleRequest(ConsumerRecords<String, Contact> records, Context context) {
        LOGGER.info("=== AvroKafkaHandler called ===");
        LOGGER.info("Event object: {}", records);
        LOGGER.info("Number of records: {}", records.count());
        
        for (ConsumerRecord<String, Contact> record : records) {
            LOGGER.info("Processing record - Topic: {}, Partition: {}, Offset: {}", 
                       record.topic(), record.partition(), record.offset());
            LOGGER.info("Record key: {}", record.key());
            LOGGER.info("Record value: {}", record.value());
            
            if (record.value() != null) {
                Contact contact = record.value();
                LOGGER.info("Contact details - firstName: {}, zip: {}", 
                           contact.getFirstname(), contact.getZip());
            }
        }
        
        LOGGER.info("=== AvroKafkaHandler completed ===");
        return "OK";
    }
}
Produce and consumer records

To send messages to Kafka, there is a LambdaMSKProducerJava function.

  1. Invoke the function from the Lambda console or CLI within the EC2 instance.
    sam remote invoke LambdaMSKProducerJavaFunction --region $AWS_REGION \
    	--stack-name msk-lambda-schema-avro-java-sam

  2. You can view the Producer logs to see the 10 records produced.The consumer Lambda function processes the records.
  3. View the consumer Lambda function logs using the Amazon CloudWatch logs console or CLI within the EC2 instance.
    sam logs --name LambdaMSKConsumerJavaFunction \
    	--stack-name msk-lambda-schema-avro-java-sam --region $AWS_REGION

The Lambda function processes and logs only the records that match the filter FILTER. The Avro binary data is deserialized using Powertools for AWS Lambda. You should see the function logs showing each record processed with the decoded keys and values.


Figure 3: Lambda consumer logs showing Avro processing

Cleaning up

You can clean up the example Lambda function by running the sam delete command.

sam delete

If you created the Amazon MSK cluster and EC2 client instance, then navigate to the CloudFormation console, choose the stack, and choose Delete.

Performance and cost considerations

Schema validation and deserialization can add processing time before your function invocation. However, this overhead is typically minimal when compared to the benefits. ESM caching minimizes schema registry API calls. Using filtering allows you to reduce costs, depending on how effectively your filtering rules eliminate irrelevant events. This feature simplifies the operational overhead of managing schema registry integration code so teams can focus on business logic rather than infrastructure concerns.

Error handling and monitoring

If schema registries become temporarily unavailable, then cached schemas allow event processing to continue until the registry is available again. Authentication failures generate error messages with automatic retry logic. Schema evolution happens seamlessly as Lambda automatically detects and fetches new versions.

If events fail validation or deserialization, they are routed to your configured failure destinations. For Amazon SQS and Amazon SNS destinations, the service sends metadata about the failure. For Amazon S3 destinations, both metadata and the original serialized payload are included for detailed analysis.

You can use standard Lambda monitoring, with more CloudWatch metrics providing visibility into schema validation success rates, registry API usage, and filtering effectiveness.

Conclusion

AWS Lambda now supports Avro and Protobuf formats for Kafka event processing in Provisioned Mode for Kafka ESM. This enables schema validation, event filtering, and integration with both Amazon MSK, Confluent, and self-managed Kafka clusters. Whether you’re building new Kafka applications or migrating existing consumers to Lambda, this native schema registry integration streamlines processing pipelines.

For more information about the Lambda Kafka integration capabilities, go to the learning guide, Lambda ESM documentation. To learn about Lambda pricing, such as Provisioned Mode costs, visit the Lambda pricing page.

For more serverless learning resources, visit Serverless Land.

Secure access to a cross-account Amazon MSK cluster from Amazon MSK Connect using IAM authentication

Post Syndicated from Venkata Sai Mahesh Swargam original https://aws.amazon.com/blogs/big-data/secure-access-to-a-cross-account-amazon-msk-cluster-from-amazon-msk-connect-using-iam-authentication/

Amazon Managed Streaming for Apache Kafka (MSK) Connect is a fully managed, scalable, and highly available service that enables the streaming of data between Apache Kafka and other data systems. Amazon MSK Connect is built on top of Kafka Connect, an open-source framework that provides a standard way to connect Kafka with external data systems. Kafka Connect supports a variety of connectors, which are used to stream data in and out of Kafka. MSK Connect extends the capabilities of Kafka Connect by providing a managed service with added security features, straightforward configuration, and automatic scaling capabilities, enabling businesses to focus on their data streaming needs without the overhead of managing the underlying infrastructure.

In some use cases, you might need to use an MSK cluster in one AWS account, but MSK Connect is located in a separate account. In this post, we demonstrate how to create a connector to achieve this use case. At the time of writing, MSK Connect connectors can be created only for MSK clusters that have AWS Identity and Access Management (IAM) role-based authentication or no authentication. We demonstrate how to implement IAM authentication after establishing network connectivity. IAM provides enhanced security measures, making sure your systems are protected against unauthorized access.

Solution overview

The connector can be configured for a variety of purposes, such as sinking data to an Amazon Simple Storage Service (Amazon S3) bucket, tracking the source database changes, or serving as a migration tool such as MirrorMaker2 on MSK Connect to transfer data from a source cluster to a target cluster this is located in a different account.

The following diagram illustrates a use case using Debezium and Amazon S3 source connectors.

The following diagram illustrates using S3 Sink and migration to a cross-account failover cluster using a MirrorMaker connector deployed on MSK Connect.

Currently MSK Connect connectors can be created only for MSK clusters which have IAM role-based authentication or no authentication. In this blog, I’ll guide you through the essential steps for implementing the industry-recommended IAM (Identity and Access Management) authentication after establishing network connectivity. IAM provides enhanced security measures, ensuring your systems are protected against unauthorized access.

The launch of multi-VPC private connectivity (powered by AWS PrivateLink) and cluster policy support for MSK clusters simplifies the connectivity of Kafka clients to brokers. By enabling this feature on the MSK cluster, you can use the cluster-based policy to manage all access control centrally in one place. In this post, we cover the process of enabling this feature on the source MSK cluster.

We don’t fully utilize the multi-VPC connectivity provided by this new feature because that requires you to use different bootstrap URLs with port numbers (14001:3) that are not supported by MSK Connect as of writing of this post. We explore a secure network connectivity solution that uses private connectivity patterns, as detailed in How Goldman Sachs builds cross-account connectivity to their Amazon MSK clusters with AWS PrivateLink.

Connecting to a cross-account MSK cluster from MSK Connect involves the following steps.

Steps to configure the MSK cluster in Account A:

  1. Enable the multi-VPC private connectivity(Private Link) feature for IAM authentication scheme that is enabled for your MSK cluster.
  2. Configure the cluster policy to allow a cross-account connector.
  3. Implement one of the preceding network connectivity patterns according to your use case to establish the connectivity with the Account B VPC and make network changes accordingly.

Steps to configure the MSK connector in Account B:

  1. Create an MSK connector in private subnets using the AWS Command Line Interface (AWS CLI).
  2. Verify the network connectivity from Account A and make network changes accordingly.
  3. Check the destination service to verify the incoming data.

Prerequisites

To follow along with this post, you should have an MSK cluster in one AWS account and MSK Connect in a separate account.

Set up the MSK cluster setup in Account A:

In this post, we only show the important steps that are required to enable the multi-VPC feature on an MSK cluster:

  1. Create a provisioned MSK cluster in Account A’s VPC with the following considerations, which are required for the multi-VPC feature:
    • Cluster version must be 2.7.1 or higher.
    • Instance type must be m5.large or higher.
    • Authentication should be IAM (you must not enable unauthenticated access for this cluster).
  2. After you create the cluster, go to the Networking settings section of your cluster and choose Edit. Then choose Turn on multi-VPC connectivity.

  1. Select IAM role-based authentication and choose Turn on selection.

It might take around 30 minutes to enable. This step is required to enable the cluster policy feature that allows the cross-account connector to access the MSK cluster.

  1. After it has been enabled, scroll down to Security settings and choose Edit cluster policy.
  2. Define your cluster policy and choose Save changes.

  1. The new cluster policy allows for defining a Basic or Advanced cluster policy. With the Basic option, it only allows CreateVPCConnection, GetBootstrapBrokers, DescribeCluster, and DescribeClusterV2 actions that are required for creating the cross-VPC connectivity to your cluster. However, we have to use Advanced to allow more actions that are required by the MSK Connector. The policy should be as follows:
    {
    
        "Version": "2012-10-17",
        "Statement": [{
            "Effect": "Allow",
            "Principal": {
                "AWS": "Connector-AccountId"
            },
            "Action": [
                "kafka:CreateVpcConnection",
                "kafka:GetBootstrapBrokers",
                "kafka:DescribeCluster",
                "kafka:DescribeClusterV2",
                "kafka-cluster:Connect",
                "kafka-cluster:DescribeCluster",
                "kafka-cluster:ReadData",
                "kafka-cluster:DescribeTopic",
                "kafka-cluster:WriteData",
                "kafka-cluster:CreateTopic",
                "kafka-cluster:AlterGroup",
                "kafka-cluster:DescribeGroup"
            ],
    "Resource": [
                    "arn:aws:kafka:<region>:<Cluster-AccountId>:cluster/<cluster-name>/<uuid>",
                    "arn:aws:kafka:<region>:<Cluster-AccountId>:topic/<cluster-name>/<uuid>/<specific-topic-name>",
                    "arn:aws:kafka:<region>:<Cluster-AccountId>:group/<cluster-name>/<uuid>/<specific-group-name>"
                ]
        }]
    }

You might need to modify the preceding permissions to limit access to your resources (topics, groups). Also, you can restrict access to a specific connector by giving the connector IAM role, or you can mention the account number to allow the connectors in that account.

Now the cluster is ready. However, you need to make sure of the network connectivity between the cross-account connector VPC and the MSK cluster VPC.

If you’re using VPC peering or Transit Gateway while connecting to MSK Connect either from cross-account or the same account, do not configure your connector to reach the peered VPC resources with IPs in the following CIDR ranges (for more details, see Connecting from connectors):

  • 10.99.0.0/16
  • 192.168.0.0/16
  • 172.21.0.0/16

In the MSK cluster security group, make sure you allowed port 9098 from Account B network resources and make changes in the subnets according to your network connectivity pattern.

Set up the MSK connector in Account B:

In this section, we demonstrate how to use the S3 Sink connector. However, you can use a different connector according to your use case and make the changes accordingly.

  1. Create an S3 bucket (or use an existing bucket).
  2. Make sure that the VPC that you’re using in this account has a security group and private subnets. If your connector for MSK Connect needs access to the internet, refer to Enable internet access for Amazon MSK Connect.
  3. Verify the network connectivity between Account A and Account B by using the telnet command to the broker endpoints with port 9098.
  4. Create an S3 VPC endpoint.
  5. Create a connector plugin according to your connector plugin provider (confluent or lenses). Make a note of the custom plugin Amazon Resource Name (ARN) to use in a later step.
  6. Create an IAM role for your connector to allow access to your S3 bucket and the MSK cluster.
    • The IAM role’s trust relationship should be as follows:
      {
          "Version": "2012-10-17",
          "Statement": [
              {
                  "Effect": "Allow",
                  "Principal": {
                      "Service": "kafkaconnect.amazonaws.com"
                  },
                  "Action": "sts:AssumeRole"
              }
          ]
      }

    • Add the following S3 access policy to your IAM role:
      {
          "Version": "2012-10-17",
          "Statement": [{
              "Effect": "Allow",
              "Action": [
                  "s3:ListAllMyBuckets",
                  "s3:ListBucket",
                  "s3:GetBucketLocation",
                  "s3:DeleteObject",
                  "s3:PutObject",
                  "s3:GetObject",
                  "s3:AbortMultipartUpload",
                  "s3:ListMultipartUploadParts",
                  "s3:ListBucketMultipartUploads"
              ],
              "Resource": [
                              "arn:aws:s3:::<destination-bucket>",
                           "arn:aws:s3:::<destination-bucket>/*"
              ],
                 "Condition": {
              "StringEquals": {
                     "aws:SourceVpc": "vpc-xxxx"
                     }
                     }
          }]
      }

    • The following policy contains the required actions by the connector:
      {
      "Version": "2012-10-17",
      "Statement": [
         {
              "Effect": "Allow",
              "Action": [
                  "kafka-cluster:Connect",
                  "kafka-cluster:DescribeCluster",
                  "kafka-cluster:ReadData",
                  "kafka-cluster:DescribeTopic",
                  "kafka-cluster:WriteData",
                  "kafka-cluster:CreateTopic",
                  "kafka-cluster:AlterGroup",
                  "kafka-cluster:DescribeGroup"
              ],
              "Resource": [
                  "arn:aws:kafka:<region>:<Cluster-AccountId>:cluster/<cluster-name>/<uuid>",
                  "arn:aws:kafka:<region>:<Cluster-AccountId>:topic/<cluster-name>/<uuid>/<specific-topic-name>",
                  "arn:aws:kafka:<region>:<Cluster-AccountId>:group/<cluster-name>/<uuid>/<specific-group-name>"
              ]
          }
      ]
      }

You might need to modify the preceding permissions to limit access to your resources (topics, groups)

Finally, it’s time to create the MSK connector. Because the Amazon MSK console doesn’t allow viewing MSK clusters in other accounts, we show you how to use the AWS CLI instead. We also use basic Amazon S3 configuration for testing purposes. You might need to modify the configuration according to your connector’s use case.

  1. Create a connector using the AWS CLI with the following command with the required parameters of the connector, along with Account A’s MSK cluster broker endpoints:
    aws kafkaconnect create-connector \
    --capacity "autoScaling={maxWorkerCount=2,mcuCount=1,minWorkerCount=1,scaleInPolicy={cpuUtilizationPercentage=10},scaleOutPolicy={cpuUtilizationPercentage=80}}" \
    --connector-configuration \
    "connector.class=io.confluent.connect.s3.S3SinkConnector, \
    s3.region=<region>, \
    schema.compatibility=NONE, \
    flush.size=2, \
    tasks.max=1, \
    topics=<MSK-Cluster-topic>, \
    security.protocol=SASL_SSL, \
    s3.compression.type=gzip, \
    format.class=io.confluent.connect.s3.format.json.JsonFormat, \
    sasl.mechanism=AWS_MSK_IAM, \
    sasl.jaas.config=software.amazon.msk.auth.iam.IAMLoginModule required, \
    sasl.client.callback.handler.class=software.amazon.msk.auth.iam.IAMClientCallbackHandler, \
    value.converter=org.apache.kafka.connect.storage.StringConverter, \
    storage.class=io.confluent.connect.s3.storage.S3Storage, \
    s3.bucket.name=<s3-bucket-name>, \
    timestamp.extractor=Record, \
    key.converter=org.apache.kafka.connect.storage.StringConverter" \
    --connector-name "Connector-name" \
    --kafka-cluster '{"apacheKafkaCluster": {"bootstrapServers": "<broker-strings>:9098","vpc": {"securityGroups": ["sg-0b36a015789f859a3"],"subnets": ["subnet-07950da1ebb8be6d8","subnet-026a729668f3f9728"]}}}' \
    --kafka-cluster-client-authentication "authenticationType=IAM" \
    --kafka-cluster-encryption-in-transit "encryptionType=TLS" \
    --kafka-connect-version "2.7.1" \
    --log-delivery workerLogDelivery='{cloudWatchLogs={enabled=true,logGroup="<MSKConnect-log-group-name>"}}' \
    --plugins "customPlugin={customPluginArn=<Custom-Plugin-ARN>,revision=1}" \
    --service-execution-role-arn "<IAM-role-ARN>"

  2. After you create the connector, connect the producer to your topic and insert data into it. In the following code, we use a Kafka client to insert data for testing purposes:
    bin/kafka-console-producer.sh --broker-list <broker-string> --producer.config client.properties --topic <topic-name>

If everything is set up correctly, you should see the data in your destination S3 bucket. If not, check the troubleshooting tips in the following section.

Troubleshooting tips

After deploying the connector, if it’s in the CREATING state on the connector details page, access the Amazon CloudWatch log group specified in your connector creation request. Review the logs for any errors. If no errors are found, wait for the connector to complete its creation process.

Additionally, make sure the IAM roles have their required permissions, and check the security groups and NACLs for proper connectivity between VPCs.

Clean up

When you’re done testing this solution, clean up any unwanted resources to avoid ongoing charges

Conclusion

In this post, we demonstrated how to create an MSK connector when you need to use an MSK cluster in one AWS account, but MSK Connect is located in a separate account. This architecture includes an S3 Sink connector for demonstration purposes, but it can accommodate other types of sink and source connectors. Additionally, this architecture focuses solely on IAM authenticated connectors. If an unauthenticated connector is desired, the multi-VPC connectivity (PrivateLink) and cluster policy components can be ignored. The remaining process, which involves creating a network connection between the account VPCs, remains the same.

Try out the solution for yourself, and let us know your questions and feedback in the comments section.

Check out more AWS Partners or contact an AWS Representative to learn how we can help accelerate your business.


About the Author

Venkata Sai Mahesh Swargam is a Cloud Engineer at AWS in Hyderabad. He specializes in Amazon MSK and Amazon Kinesis services. Mahesh is dedicated to helping customers by providing technical guidance and solving issues related to their Amazon MSK architectures. In his free time, he enjoys being with family and traveling around the world.

Build a secure serverless streaming pipeline with Amazon MSK Serverless, Amazon EMR Serverless and IAM

Post Syndicated from Shubham Purwar original https://aws.amazon.com/blogs/big-data/build-a-secure-serverless-streaming-pipeline-with-amazon-msk-serverless-amazon-emr-serverless-and-iam/

The exponential growth and vast volume of streaming data have made it a vital resource for organizations worldwide. To unlock its full potential, real-time analytics are essential for extracting actionable insights. Derived from a wide range of sources, including social media, Internet of Things (IoT) sensors, and user interactions, streaming data empowers businesses to respond promptly to emerging trends and events, make informed decisions, and stay ahead of the competition.

Commonly streaming applications use Apache Kafka for data ingestion and Apache Spark Structured Streaming for processing. However, integrating and securing these components poses considerable challenges for users. The complexity of managing certificates, keystores, and TLS configurations to connect Spark Streaming to Kafka brokers demands specialized expertise. A managed, serverless framework would greatly simplify this process, alleviating the need for manual configuration and streamlining the integration of these critical components.

To simplify the management and security of traditional streaming architectures, you can use Amazon Managed Streaming for Apache Kafka (Amazon MSK). This fully managed service simplifies data ingestion and processing. Amazon MSK Serverless alleviates the need for cluster management and scaling, and further enhances security by integrating AWS Identity and Access Management (IAM) for authentication and authorization. This consolidated approach replaces complex certificate and key management require by TLS client authentication through AWS Certificate Manager, streamlining operations and bolstering data protection. For instance, when a client attempts to write data to the cluster, MSK Serverless verifies both the client’s identity and its permissions using IAM.

For efficient data processing, you can use Amazon EMR Serverless with a Spark application built on the Spark Structured Streaming framework, enabling near real-time data processing. This setup seamlessly handles large volumes of data from MSK Serverless, using IAM authentication for secure and swift data processing.

The post demonstrates a comprehensive, end-to-end solution for processing data from MSK Serverless using an EMR Serverless Spark Streaming job, secured with IAM authentication. Additionally, it demonstrates how to query the processed data using Amazon Athena, providing a seamless and integrated workflow for data processing and analysis. This solution enables near real-time querying of the latest data processed from MSK Serverless and EMR Serverless using Athena, providing instant insights and analytics.

Solution overview

The following diagram illustrates the architecture that you implement through this post.

The workflow consists of the following steps:

  1. The architecture begins with an MSK Serverless cluster set up with IAM authentication. An Amazon Elastic Compute Cloud (Amazon EC2) instance runs a Python script producer.py that acts as a data producer, sending sample data to a Kafka topic within the cluster.
  2. The Spark Streaming job retrieves data from the Kafka topic, stores it in Amazon Simple Storage Service (Amazon S3), and creates a corresponding table in the AWS Glue Data Catalog. As it continuously consumes data from the Kafka topic, the job stays up-to-date with the latest streaming data. With checkpointing enabled, the job tracks processed records, allowing it to resume from where it left off in case of a failure, providing seamless data processing.
  3. To analyze this data, users can use Athena, a serverless query service. Athena enables interactive SQL-based exploration of data directly in Amazon S3 without the need for complex infrastructure management.

Prerequisites

Before getting started, make sure you have the following:

  • An active AWS account with billing enabled
  • An IAM user with administrator access (AdministratorAccess policy) or specific permissions to create and manage resources such as a virtual private cloud (VPC), subnet, security group, IAM roles, NAT gateway, internet gateway, EC2 client, MSK Serverless, EMR Serverless, Amazon EMR Studio, and S3 buckets
  • Sufficient VPC capacity in your chosen AWS Region

Although using an IAM user with administrator access will work, it’s recommended to follow the principle of least privilege in production environments by creating custom IAM policies with only the necessary permissions. The IAM user we create has the AdministrativeAccess policy attached to it. However, you might not need such elevated access.

For this post, we create the solution resources in the us-east-2 Region using AWS CloudFormation templates. In the following sections, we show you how to configure your resources and implement the solution.

Create MSK Serverless and EMR Serverless resources

The vpc-msk-emr-serverless-studio.yaml stack creates a VPC, subnet, security group, IAM roles, NAT gateway, internet gateway, EC2 client, MSK Serverless, EMR Serverless, EMR Studio, and S3 buckets. To create the solution resources, complete the following steps:

  1. Launch the stack vpc-msk-emr-serverless-studio using the CloudFormation template:

  1. Provide the parameter values as listed in the following table.
Parameters Description Sample value
EnvironmentName An environment name that is prefixed to resource names. msk-emr-serverless-pipeline
InstanceType Amazon MSK client EC2 instance type. t2.micro
LatestAmiId Latest AMI ID of Amazon Linux 2023 for ec2 instance. You can use the default value. /aws/service/ami-amazon-linux-latest/al2023-ami-kernel-6.1-x86_64
VpcCIDR IP range (CIDR notation) for this VPC. 10.192.0.0/16
PublicSubnet1CIDR IP range (CIDR notation) for the public subnet in the first Availability Zone. 10.192.10.0/24
PublicSubnet2CIDR IP range (CIDR notation) for the public subnet in the second Availability Zone. 10.192.11.0/24
PrivateSubnet1CIDR IP range (CIDR notation) for the private subnet in the first Availability Zone. 10.192.20.0/24
PrivateSubnet2CIDR IP range (CIDR notation) for the private subnet in the second Availability Zone. 10.192.21.0/24

The stack creation process can take approximately 10 minutes to complete. You can check the Outputs tab for the stack after the stack is created.

Next, you set up the data ingestion to the Kafka topic from the Kafka EC2 instance.

Produce records to Kafka topic

Complete the following steps to set up data ingestion:

  1. On the Amazon EC2 console, go to the EC2 instance that you created using the CloudFormation template.

  1. Log in to the EC2 instance using Session Manager, a capability of AWS Systems Manager.
  2. Choose the instance msk-emr-serverless-blog and then choose Connect.

  1. Create a Kafka topic in MSK Serverless from the EC2 instance.
    1. In the following export command, replace my-endpoint with the MSKBootstrapServers value from the CloudFormation stack output:
      $ sudo su - ec2-user
      $ BS=<your-msk-serverless-endpoint (e.g.) boot-xxxxxx.yy.kafka-serverless.us-east-2.amazonaws.com:9098>

    2. Run the following command on the EC2 instance to create a topic called sales_data_topic:

Kafka client already installed at ec2-user home directory (/home/ec2-user) with MSK IAM Authentication jar and client configuration also created (/home/ec2-user/kafka_2.12-2.8.1/bin/client.properties) with IAM authentication properties.

The following code shows the contents of client.properties:

security.protocol=SASL_SSL
sasl.mechanism=AWS_MSK_IAM
sasl.jaas.config=software.amazon.msk.auth.iam.IAMLoginModule required;
sasl.client.callback.handler.class=software.amazon.msk.auth.iam.IAMClientCallbackHandler

/home/ec2-user/kafka_2.12-2.8.1/bin/kafka-topics.sh \
--bootstrap-server $BS \
--command-config /home/ec2-user/kafka_2.12-2.8.1/bin/client.properties \
--create --topic sales_data_topic \
--partitions 10

Created topic sales_data_topic.
  1. Run the following command to produce records to the Kafka topic using the syntheticSalesDataProducer.py Python script present in EC2 instance. Update the Region accordingly.
nohup python3 -u syntheticSalesDataProducer.py --num_records 1000 \
--sales_data_topic sales_data_topic --bootstrap_server $BS \
--region=us-east-2 > syntheticSalesDataProducer.log &

Understanding Amazon MSK IAM authentication with EMR Serverless

Amazon MSK IAM authentication enables secure authentication and authorization for Kafka clusters (MSK Serverless) using IAM roles. When integrating with EMR Serverless Spark Streaming, Amazon MSK IAM authentication allows Spark jobs to access Kafka topics securely, using IAM roles for fine-grained access control. This provides secure data processing and streaming.

IAM policy configuration

To enable EMR Serverless jobs to authenticate with an MSK Serverless cluster using IAM, you need to attach specific Kafka-related IAM permissions to the EMR Serverless job execution role. These permissions allow the job to perform essential operations on the Kafka cluster, topics, and consumer groups.The following IAM policy must be attached to the EMR Serverless job execution role to enable necessary permissions:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Action": [
                "kafka-cluster:Connect",
                "kafka-cluster:DescribeCluster"
            ],
            "Resource": [
                "arn:aws:kafka:<AWS-REGION>:<ACCOUNTID>:cluster/<SERVERLESS_CLUSTER_NAME>/<ID>"
            ],
            "Effect": "Allow"
        },
        {
            "Action": [
                "kafka-cluster:CreateTopic",
                "kafka-cluster:DescribeTopic",
                "kafka-cluster:WriteData",
                "kafka-cluster:ReadData"
            ],
            "Resource": [
                "arn:aws:kafka:<AWS-REGION>:<ACCOUNTID>:topic/<SERVERLESS_CLUSTER_NAME>/*/*"
            ],
            "Effect": "Allow"
        },
        {
            "Action": [
                "kafka-cluster:AlterGroup",
                "kafka-cluster:DescribeGroup"
            ],
            "Resource": [
                "arn:aws:kafka:<AWS-REGION>:<ACCOUNTID>:group/<SERVERLESS_CLUSTER_NAME>/*/*"
            ],
            "Effect": "Allow"
        }
    ]
}

This code refers to the following actions:

  • Connect, DescribeCluster – Required to initiate a secure connection and obtain metadata
  • DescribeTopic, ReadData, WriteData – Enables data consumption and production
  • CreateTopic (optional) – Allows dynamic topic creation
  • AlterGroup, DescribeGroup – Needed for consumer group management in streaming jobs

These permissions make sure that the Spark Streaming job can securely authenticate and interact with MSK Serverless resources using its IAM role.

Required dependencies

To enable Amazon MSK IAM authentication in Spark (especially on EMR Serverless), specific JAR dependencies must be included in your Spark Streaming job using sparkSubmitParameters:

  • spark-sql-kafka-0-10_2.12 – This is the Kafka connector for Spark Structured Streaming. It provides the DataFrame API to read from and write to Kafka.
  • aws-msk-iam-auth – This JAR provides the IAM authentication mechanism required to connect to MSK Serverless using the AWS_MSK_IAM SASL mechanism.

You can include these dependencies directly by specifying them in the --packages argument when submitting the EMR Serverless job. For example:

--packages org.apache.spark:spark-sql-kafka-0-10_2.12:3.5.1,software.amazon.msk:aws-msk-iam-auth:2.2.0

When the job is submitted, EMR Serverless will automatically download these JARs from Maven Central (or another configured repository) at runtime. You don’t need to bundle them manually unless offline usage or specific versions are required.

Spark Streaming job configuration for Amazon MSK IAM authentication

In your Spark Streaming application, configure the Kafka source with SASL properties to enable IAM based authentication. The following code shows the relevant configuration:

topic_df = (spark.readStream
    .format("kafka")
    .option("kafka.bootstrap.servers", kafka_bootstrap_servers)
    .option("subscribe", topic_input)
    .option("startingOffsets", "earliest")
    .option("kafka.security.protocol","SASL_SSL")
    option("kafka.sasl.mechanism","AWS_MSK_IAM")
    .option("kafka.sasl.jaas.config","software.amazon.msk.auth.iam.IAMLoginModule required;")
    .option("kafka.sasl.client.callback.handler.class","software.amazon.msk.auth.iam.IAMClientCallbackHandler")
    .load()
    .selectExpr("CAST(value AS STRING)")
    )

Key properties include:

  • kafka.security.protocol = SASL_SSL – Enables encrypted communication over SSL with SASL authentication
  • kafka.sasl.mechanism = AWS_MSK_IAM – Tells Kafka to use the IAM based SASL mechanism
  • kafka.sasl.jaas.config = software.amazon.msk.auth.iam.IAMLoginModule required; – Specifies the login module provided by AWS for IAM integration
  • kafka.sasl.client.callback.handler.class = software.amazon.msk.auth.iam.IAMClientCallbackHandler – Handles the actual signing and authentication using the IAM role

With these settings, Spark uses the IAM credentials attached to the EMR Serverless job execution role to authenticate to MSK Serverless without needing additional credentials, certificates, or secrets.

Data processing using an EMR Serverless streaming job with Amazon MSK IAM authentication

Complete the following steps to run a Spark Streaming job to process the data from MSK Serverless:

  1. Submit the Spark Streaming job to EMR Serverless using the AWS Command Line Interface (AWS CLI), which is already installed on the EC2 instance.
  2. Log in to the EC2 instance using Session Manager. Choose the instance msk-emr-serverless-blog and then choose Connect.
  3. Run the following command to submit the streaming job. Provide the parameters from the CloudFormation stack output.
sudo su - ec2-user

aws emr-serverless start-job-run \
--application-id <APPLICATION ID> \
--execution-role-arn <EXECUTION ROLE ARN> \
--mode 'STREAMING' \
--job-driver '{
"sparkSubmit": {
"entryPoint": "s3://<EMR BLOG SCRIPT BUCKET>/emr_pyspark_streaming_script/pysparkStreamingBlog.py",
"entryPointArguments":["--topic_input","sales_data_topic","--kafka_bootstrap_servers","<BOOTSTRAP URL WITH PORT>","--output_s3_path","s3://<EMR STREAMING OUTPUT BUCKET>/output/sales-order-data/","--checkpointLocation","s3://<EMR STREAMING OUTPUT BUCKET>/checkpointing/checkpoint-sales-order-data/","--database_name","emrblog","--table_name","sales_order_data"],
"sparkSubmitParameters": "--conf spark.hadoop.hive.metastore.client.factory.class=com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory --conf spark.executor.cores=2 --conf spark.executor.memory=5g --conf spark.driver.cores=2 --conf spark.driver.memory=5g --conf spark.executor.instances=5 --packages org.apache.spark:spark-sql-kafka-0-10_2.12:3.5.1,software.amazon.msk:aws-msk-iam-auth:2.2.0"
}}'
  1. After you submit the job, log in to EMR Studio using the URL in the EmrServerlessStudioURL value from the CloudFormation stack output.
  2. In the navigation pane, choose Applications under Serverless.
  3. Choose the application ID in the EmrServerlessSparkApplicationID value from the CloudFormation stack output.
  4. On the Streaming job runs tab, verify that the job has been submitted and wait for it to begin running.

Validate the data in Athena

After the EMR Serverless Spark Streaming job ran and created the table for the processed data in the Data Catalog, follow these steps to validate the data using Athena:

  1. On the Athena console, open the query editor.
  2. Choose the Data Catalog as the data source.
  3. Choose the database emrblog that the streaming job created.
  4. To validate the data, run the following query:
SELECT 
    DATE_TRUNC('minute', date) AS minute_window, 
    ROUND(SUM(total_amount), 2) AS total_amount
FROM 
    emrblog.sales_order_data
WHERE 
    DATE_TRUNC('day', date) = CURRENT_DATE
GROUP BY 
    DATE_TRUNC('minute', date)
ORDER BY 
    minute_window DESC;

Clean up

To clean up your resources, complete the following steps:

  1. Log in to EMR Studio using the URL from the EmrServerlessStudioURL value in the CloudFormation stack output.
  2. In the navigation pane, choose Applications under Serverless.
  3. Choose the application ID from the EmrServerlessSparkApplicationID value in the CloudFormation stack output.
  4. On the Streaming job runs tab, select the job that has been running and cancel the job run.
  5. On the AWS CloudFormation console, delete the CloudFormation stack vpc-msk-emr-serverless-studio.

Conclusion

In this post, we showcased a serverless pipeline for streaming data with IAM authentication, empowering you to focus on deriving insights from your analytics. You can customize the EMR Serverless Spark Streaming code to apply transformations and filters, so only valid data is loaded into Amazon S3. This solution combines the power of Amazon EMR Spark Serverless streaming with MSK Serverless, securely integrated through IAM authentication. Now you can streamline your streaming processes without the complexity of managing Amazon MSK and Amazon EMR Spark Streaming integrations.


About the Authors

Shubham Purwar is an AWS Analytics Specialist Solution Architect. He helps organizations unlock the full potential of their data by designing and implementing scalable, secure, and high-performance analytics solutions on the AWS platform. With deep expertise in AWS analytics services, he collaborates with customers to uncover their distinct business requirements and create customized solutions that deliver actionable insights and drive business growth. In his free time, Shubham loves to spend time with his family and travel around the world.

Nitin Kumar is a Cloud Engineer (ETL) at AWS, specialized in AWS Glue. With a decade of experience, he excels in aiding customers with their big data workloads, focusing on data processing and analytics. He is committed to helping customers overcome ETL challenges and develop scalable data processing and analytics pipelines on AWS. In his free time, he likes to watch movies and spend time with his family.

Prashanthi Chinthala is a Cloud Engineer (DIST) at AWS. She helps customers overcome EMR challenges and develop scalable data processing and analytics pipelines on AWS.

Build multi-Region resilient Apache Kafka applications with identical topic names using Amazon MSK and Amazon MSK Replicator

Post Syndicated from Subham Rakshit original https://aws.amazon.com/blogs/big-data/build-multi-region-resilient-apache-kafka-applications-with-identical-topic-names-using-amazon-msk-and-amazon-msk-replicator/

Resilience has always been a top priority for customers running mission-critical Apache Kafka applications. Amazon Managed Streaming for Apache Kafka (Amazon MSK) is deployed across multiple Availability Zones and provides resilience within an AWS Region. However, mission-critical Kafka deployments require cross-Region resilience to minimize downtime during service impairment in a Region. With Amazon MSK Replicator, you can build multi-Region resilient streaming applications to provide business continuity, share data with partners, aggregate data from multiple clusters for analytics, and serve global clients with reduced latency. This post explains how to use MSK Replicator for cross-cluster data replication and details the failover and failback processes while keeping the same topic name across Regions.

MSK Replicator overview

Amazon MSK offers two cluster types: Provisioned and Serverless. Provisioned cluster supports two broker types: Standard and Express. With the introduction of Amazon MSK Express brokers, you can now deploy MSK clusters that significantly reduce recovery time by up to 90% while delivering consistent performance. Express brokers provide up to 3 times the throughput per broker and scale up to 20 times faster compared to Standard brokers running Kafka. MSK Replicator works with both broker types in Provisioned clusters and along with Serverless clusters.

MSK Replicator supports an identical topic name configuration, enabling seamless topic name retention during both active-active or active-passive replication. This avoids the risk of infinite replication loops commonly associated with third-party or open source replication tools. When deploying an active-passive cluster architecture for regional resilience, where one cluster handles live traffic and the other acts as a standby, an identical topic configuration simplifies the failover process. Applications can transition to the standby cluster without reconfiguration because topic names remain consistent across the source and target clusters.

To set up an active-passive deployment, you have to enable multi-VPC connectivity for the MSK cluster in the primary Region and deploy an MSK Replicator in the secondary Region. The replicator will consume data from the primary Region’s MSK cluster and asynchronously replicate it to the secondary Region. You connect the clients initially to the primary cluster but fail over the clients to the secondary cluster in the case of primary Region impairment. When the primary Region recovers, you deploy a new MSK Replicator to replicate data back from the secondary cluster to the primary. You need to stop the client applications in the secondary Region and restart them in the primary Region.

Because replication with MSK Replicator is asynchronous, there is a possibility of duplicate data in the secondary cluster. During a failover, consumers might reprocess some messages from Kafka topics. To address this, deduplication should occur on the consumer side, such as by using an idempotent downstream system like a database.

In the next sections, we demonstrate how to deploy MSK Replicator in an active-passive architecture with identical topic names. We provide a step-by-step guide for failing over to the secondary Region during a primary Region impairment and failing back when the primary Region recovers. For an active-active setup, refer to Create an active-active setup using MSK Replicator.

Solution overview

In this setup, we deploy a primary MSK Provisioned cluster with Express brokers in the us-east-1 Region. To provide cross-Region resilience for Amazon MSK, we establish a secondary MSK cluster with Express brokers in the us-east-2 Region and replicate topics from the primary MSK cluster to the secondary cluster using MSK Replicator. This configuration provides high resilience within each Region by using Express brokers, and cross-Region resilience is achieved through an active-passive architecture, with replication managed by MSK Replicator.

The following diagram illustrates the solution architecture.

The primary Region MSK cluster handles client requests. In the event of a failure to communicate to MSK cluster due to primary region impairment, you need to fail over the clients to the secondary MSK cluster. The producer writes to the customer topic in the primary MSK cluster, and the consumer with the group ID msk-consumer reads from the same topic. As part of the active-passive setup, we configure MSK Replicator to use identical topic names, making sure that the customer topic remains consistent across both clusters without requiring changes from the clients. The entire setup is deployed within a single AWS account.

In the next sections, we describe how to set up a multi-Region resilient MSK cluster using MSK Replicator and also show the failover and failback strategy.

Provision an MSK cluster using AWS CloudFormation

We provide AWS CloudFormation templates to provision certain resources:

This will create the virtual private cloud (VPC), subnets, and the MSK Provisioned cluster with Express brokers within the VPC configured with AWS Identity and Access Management (IAM) authentication in each Region. It will also create a Kafka client Amazon Elastic Compute Cloud (Amazon EC2) instance, where we can use the Kafka command line to create and view a Kafka topic and produce and consume messages to and from the topic.

Configure multi-VPC connectivity in the primary MSK cluster

After the clusters are deployed, you need to enable the multi-VPC connectivity in the primary MSK cluster deployed in us-east-1. This will allow MSK Replicator to connect to the primary MSK cluster using multi-VPC connectivity (powered by AWS PrivateLink). Multi-VPC connectivity is only required for cross-Region replication. For same-Region replication, MSK Replicator uses an IAM policy to connect to the primary MSK cluster.

MSK Replicator uses IAM authentication only to connect to both primary and secondary MSK clusters. Therefore, although other Kafka clients can still continue to use SASL/SCRAM or mTLS authentication, for MSK Replicator to work, IAM authentication has to be enabled.

To enable multi-VPC connectivity, complete the following steps:

  1. On the Amazon MSK console, navigate to the MSK cluster.
  2. On the Properties tab, under Network settings, choose Turn on multi-VPC connectivity on the Edit dropdown menu.

  1. For Authentication type, select IAM role-based authentication.
  2. Choose Turn on selection.

Enabling multi-VPC connectivity is a one-time setup and it can take approximately 30–45 minutes depending on the number of brokers. After this is enabled, you need to provide the MSK cluster resource policy to allow MSK Replicator to talk to the primary cluster.

  1. Under Security settings¸ choose Edit cluster policy.
  2. Select Include Kafka service principal.

Now that the cluster is enabled to receive requests from MSK Replicator using PrivateLink, we need to set up the replicator.

Create a MSK Replicator

Complete the following steps to create an MSK Replicator:

  1. In the secondary Region (us-east-2), open the Amazon MSK console.
  2. Choose Replicators in the navigation pane.
  3. Choose Create replicator.
  4. Enter a name and optional description.

  1. In the Source cluster section, provide the following information:
    1. For Cluster region, choose us-east-1.
    2. For MSK cluster, enter the Amazon Resource Name (ARN) for the primary MSK cluster.

For cross-Region setup, the primary cluster will appear disabled if the multi-VPC connectivity is not enabled and the cluster resource policy is not configured in the primary MSK cluster. After you choose the primary cluster, it automatically selects the subnets associated with primary cluster. Security groups are not required because the primary cluster’s access is governed by the cluster resource policy.

Next, you select the target cluster. The target cluster Region is defaulted to the Region where the MSK Replicator is created. In this case, it’s us-east-2.

  1. In the Target cluster section, provide the following information:
    1. For MSK cluster, enter the ARN of the secondary MSK cluster. This will automatically select the cluster subnets and the security group associated with the secondary cluster.
    2. For Security groups, choose any additional security groups.

Make sure that the security groups have outbound rules to allow traffic to your secondary cluster’s security groups. Also make sure that your secondary cluster’s security groups have inbound rules that accept traffic from the MSK Replicator security groups provided here.

Now let’s provide the MSK Replicator settings.

  1. In the Replicator settings section, enter the following information:
    1. For Topics to replicate, we keep the topics to replicate as a default value that replicates all topics from the primary to secondary cluster.
    2. For Replication starting position, we choose Earliest, so that we can get all the events from the start of the source topics.
    3. For Copy settings, select Keep the same topic names to configure the topic name in the secondary cluster as identical to the primary cluster.

This makes sure that the MSK clients don’t need to add a prefix to the topic names.

  1. For this example, we keep the Consumer group replication setting as default and set Target compression type as None.

Also, MSK Replicator will automatically create the required IAM policies.

  1. Choose Create to create the replicator.

The process takes around 15–20 minutes to deploy the replicator. After the MSK Replicator is running, this will be reflected in the status.

Configure the MSK client for the primary cluster

Complete the following steps to configure the MSK client:

  1. On the Amazon EC2 console, navigate to the EC2 instance of the primary Region (us-east-1) and connect to the EC2 instance dr-test-primary-KafkaClientInstance1 using Session Manager, a capability of AWS Systems Manager.

After you have logged in, you need to configure the primary MSK cluster bootstrap address to create a topic and publish data to the cluster. You can get the bootstrap address for IAM authentication on the Amazon MSK console under View Client Information on the cluster details page.

  1. Configure the bootstrap address with the following code:
sudo su - ec2-user

export BS_PRIMARY=<<MSK_BOOTSTRAP_ADDRESS>>
  1. Configure the client configuration for IAM authentication to talk to the MSK cluster:
echo -n "security.protocol=SASL_SSL
sasl.mechanism=AWS_MSK_IAM
sasl.jaas.config=software.amazon.msk.auth.iam.IAMLoginModule required;
sasl.client.callback.handler.class=software.amazon.msk.auth.iam.IAMClientCallbackHandler
" > /home/ec2-user/kafka/config/client_iam.properties

Create a topic and produce and consume messages to the topic

Complete the following steps to create a topic and then produce and consume messages to it:

  1. Create a customer topic:
/home/ec2-user/kafka/bin/kafka-topics.sh --bootstrap-server=$BS_PRIMARY \
--create --replication-factor 3 --partitions 3 \
--topic customer \
--command-config=/home/ec2-user/kafka/config/client_iam.properties
  1. Create a console producer to write to the topic:
/home/ec2-user/kafka/bin/kafka-console-producer.sh \
--bootstrap-server=$BS_PRIMARY --topic customer \
--producer.config=/home/ec2-user/kafka/config/client_iam.properties
  1. Produce the following sample text to the topic:
This is a customer topic
This is the 2nd message to the topic.
  1. Press Ctrl+C to exit the console prompt.
  2. Create a consumer with group.id msk-consumer to read all the messages from the beginning of the customer topic:
/home/ec2-user/kafka/bin/kafka-console-consumer.sh \
--bootstrap-server=$BS_PRIMARY --topic customer --from-beginning \
--consumer.config=/home/ec2-user/kafka/config/client_iam.properties \
--consumer-property group.id=msk-consumer

This will consume both the sample messages from the topic.

  1. Press Ctrl+C to exit the console prompt.

Configure the MSK client for the secondary MSK cluster

Go to the EC2 cluster of the secondary Region us-east-2 and follow the previously mentioned steps to configure an MSK client. The only difference from the previous steps is that you should use the bootstrap address of the secondary MSK cluster as the environment variable. Configure the variable $BS_SECONDARY to configure the secondary Region MSK cluster bootstrap address.

Verify replication

After the client is configured to talk to the secondary MSK cluster using IAM authentication, list the topics in the cluster. Because the MSK Replicator is now running, the customer topic is replicated. To verify it, let’s see the list of topics in the cluster:

/home/ec2-user/kafka/bin/kafka-topics.sh --bootstrap-server=$BS_SECONDARY \
--list --command-config=/home/ec2-user/kafka/config/client_iam.properties

The topic name is customer without any prefix.

By default, MSK Replicator replicates the details of all the consumer groups. Because you used the default configuration, you can verify using the following command if the consumer group ID msk-consumer is also replicated to the secondary cluster:

/home/ec2-user/kafka/bin/kafka-consumer-groups.sh --bootstrap-server=$BS_SECONDARY \
--list --command-config=/home/ec2-user/kafka/config/client_iam.properties

Now that we have verified the topic is replicated, let’s understand the key metrics to monitor.

Monitor replication

Monitoring MSK Replicator is very important to make sure that replication of data is happening fast. This reduces the risk of data loss in case an unplanned failure occurs. Some important MSK Replicator metrics to monitor are ReplicationLatency, MessageLag, and ReplicatorThroughput. For a detailed list, see Monitor replication.

To understand how many bytes are processed by MSK Replicator, you should monitor the metric ReplicatorBytesInPerSec. This metric indicates the average number of bytes processed by the replicator per second. Data processed by MSK Replicator consists of all data MSK Replicator receives. This includes the data replicated to the target cluster and filtered by MSK Replicator. This metric is applicable if you use Keep same topic name in the MSK Replicator copy settings. During a failback scenario, MSK Replicator starts to read from the earliest offset and replicates records from the secondary back to the primary. Depending on the retention settings, some data might exist in the primary cluster. To prevent duplicates, MSK Replicator processes the data but automatically filters out duplicate data.

Fail over clients to the secondary MSK cluster

In the case of an unexpected event in the primary Region in which clients can’t connect to the primary MSK cluster or the clients are receiving unexpected produce and consume errors, this could be a sign that the primary MSK cluster is impacted. You may notice a sudden spike in replication latency. If the latency continues to rise, it could indicate a regional impairment in Amazon MSK. To verify this, you can check the AWS Health Dashboard, though there is a chance that status updates may be delayed. Once you identify signs of a regional impairment in Amazon MSK, you should prepare to fail over the clients to the secondary region.

For critical workloads we recommend not taking a dependency on control plane actions for failover. To mitigate this risk, you could implement a pilot light deployment, where essential components of the stack are kept running in a secondary region and scaled up when the primary region is impaired. Alternatively, for faster and smoother failover with minimal downtime, a hot standby approach is recommended. This involves pre-deploying the entire stack in a secondary region so that, in a disaster recovery scenario, the pre-deployed clients can be quickly activated in the secondary region.

Failover process

To perform the failover, you first need to stop the clients pointed to the primary MSK cluster. However, for the purpose of the demo, we are using console producer and consumers, so our clients are already stopped.

In a real failover scenario, using primary Region clients to communicate with the secondary Region MSK cluster is not recommended, as it breaches fault isolation boundaries and leads to increased latency. To simulate the failover using the preceding setup, let’s start a producer and consumer in the secondary Region (us-east-2). For this, run a console producer in the EC2 instance (dr-test-secondary-KafkaClientInstance1) of the secondary Region.

The following diagram illustrates this setup.

Complete the following steps to perform a failover:

  1. Create a console producer using the following code:
/home/ec2-user/kafka/bin/kafka-console-producer.sh \
--bootstrap-server=$BS_SECONDARY --topic customer \
--producer.config=/home/ec2-user/kafka/config/client_iam.properties
  1. Produce the following sample text to the topic:
This is the 3rd message to the topic.
This is the 4th message to the topic.

Now, let’s create a console consumer. It’s important to make sure the consumer group ID is exactly the same as the consumer attached to the primary MSK cluster. For this, we use the group.id msk-consumer to read the messages from the customer topic. This simulates that we are bringing up the same consumer attached to the primary cluster.

  1. Create a console consumer with the following code:
/home/ec2-user/kafka/bin/kafka-console-consumer.sh \
--bootstrap-server=$BS_SECONDARY --topic customer --from-beginning \
--consumer.config=/home/ec2-user/kafka/config/client_iam.properties \
--consumer-property group.id=msk-consumer

Although the consumer is configured to read all the data from the earliest offset, it only consumes the last two messages produced by the console producer. This is because MSK Replicator has replicated the consumer group details along with the offsets read by the consumer with the consumer group ID msk-consumer. The console consumer with the same group.id mimic the behaviour that the consumer is failed over to the secondary Amazon MSK cluster.

Fail back clients to the primary MSK cluster

Failing back clients to the primary MSK cluster is the common pattern in an active-passive scenario, when the service in the primary region has recovered. Before we fail back clients to the primary MSK cluster, it’s important to sync the primary MSK cluster with the secondary MSK cluster. For this, we need to deploy another MSK Replicator in the primary Region configured to read from the earliest offset from the secondary MSK cluster and write to the primary cluster with the same topic name. The MSK Replicator will copy the data from the secondary MSK cluster to the primary MSK cluster. Although the MSK Replicator is configured to start from the earliest offset, it will not duplicate the data already present in the primary MSK cluster. It will automatically filter out the existing messages and will only write back the new data produced in the secondary MSK cluster when the primary MSK cluster was down. The replication step from secondary to primary wouldn’t be required if you don’t have a business requirement of keeping the data same across both clusters.

After the MSK Replicator is up and running, monitor the MessageLag metric of MSK Replicator. This metric indicates how many messages are yet to be replicated from the secondary MSK cluster to the primary MSK cluster. The MessageLag metric should come down close to 0. Now you should stop the producers writing to the secondary MSK cluster and restart connecting to the primary MSK cluster. You should also allow the consumers to read data from the secondary MSK cluster until the MaxOffsetLag metric for the consumers is not 0. This makes sure that the consumers have already processed all the messages from the secondary MSK cluster. The MessageLag metric should be 0 by this time because no producer is producing records in the secondary cluster. MSK Replicator replicated all messages from the secondary cluster to the primary cluster. At this point, you should start the consumer with the same group.id in the primary Region. You can delete the MSK Replicator created to copy messages from the secondary to the primary cluster. Make sure that the previously existing MSK Replicator is in RUNNING status and successfully replicating messages from the primary to secondary. This can be confirmed by looking at the ReplicatorThroughput metric, which should be greater than 0.

Failback process

To simulate a failback, you first need to enable multi-VPC connectivity in the secondary MSK cluster (us-east-2) and add a cluster policy for the Kafka service principal like we did before.

Deploy the MSK Replicator in the primary Region (us-east-1) with the source MSK cluster pointed to us-east-2 and the target cluster pointed to us-east-1. Configure Replication starting position as Earliest and Copy settings as Keep the same topic names.

The following diagram illustrates this setup.

After the MSK Replicator is in RUNNING status, let’s verify there is no duplicate while replicating the data from the secondary to the primary MSK cluster.

Run a console consumer without the group.id in the EC2 instance (dr-test-primary-KafkaClientInstance1) of the primary Region (us-east-1):

/home/ec2-user/kafka/bin/kafka-console-consumer.sh \
--bootstrap-server=$BS_PRIMARY --topic customer --from-beginning \
--consumer.config=/home/ec2-user/kafka/config/client_iam.properties

This should show the four messages without any duplicates. Although in the consumer we specify to read from the earliest offset, MSK Replicator makes sure the duplicate data isn’t replicated back to the primary cluster from the secondary cluster.

This is a customer topic
This is the 2nd message to the topic.
This is the 3rd message to the topic.
This is the 4th message to the topic.

You can now point the clients to start producing to and consuming from the primary MSK cluster.

Clean up

At this point, you can tear down the MSK Replicator deployed in the primary Region.

Conclusion

This post explored how to enhance Kafka resilience by setting up a secondary MSK cluster in another Region and synchronizing it with the primary cluster using MSK Replicator. We demonstrated how to implement an active-passive disaster recovery strategy while maintaining consistent topic names across both clusters. We provided a step-by-step guide for configuring replication with identical topic names and detailed the processes for failover and failback. Additionally, we highlighted key metrics to monitor and outlined actions to provide efficient and continuous data replication.

For more information, refer to What is Amazon MSK Replicator? For a hands-on experience, try out the Amazon MSK Replicator Workshop. We encourage you to try out this feature and share your feedback with us.


About the Author

Subham Rakshit is a Senior Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build streaming architectures so they can get value from analyzing their streaming data. His two little daughters keep him occupied most of the time outside work, and he loves solving jigsaw puzzles with them. Connect with him on LinkedIn.

Deploy real-time analytics with StarTree for managed Apache Pinot on AWS

Post Syndicated from Raj Ramasubbu original https://aws.amazon.com/blogs/big-data/deploy-real-time-analytics-with-startree-for-managed-apache-pinot-on-aws/

This post is cowritten with Mayank Shrivastava and Barkha Herman from StarTree.

Building a low-latency, high-concurrency, real-time online analytical processing (OLAP) solution has been previously explored on the AWS Big Data Blog, where we walked through how to build a real-time analytics solution with Apache Pinot on AWS, in which streaming sources, such as Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Kinesis Data Streams, produce events that are ingested and processed in real time within Apache Pinot.

However, this approach requires self-management of the infrastructure required to run Pinot, as well as a number of manual processes to run in production. StarTree is a managed alternative that offers similar benefits for real-time analytics use cases.

In this post, we introduce StarTree as a managed solution on AWS for teams seeking the advantages of Pinot. We highlight the key distinctions between open-source Pinot and StarTree, and provide valuable insights for organizations considering a more streamlined approach to their real-time analytics infrastructure.

By examining these aspects, you can make an informed decision between open source Pinot and StarTree for your specific real-time analytics needs.

StarTree overview

One of the founders of Apache Pinot, Kishore Gopalakrishna, launched StarTree to equip organizations globally with the power of real-time data and build a fully managed platform for real-time analytics. Handling over 1 billion queries per week and ingesting over 1 million events per second, StarTree Cloud removes the burden of infrastructure management so companies can focus on delivering real-time insights to end-users.

Open source Pinot requires in-house expertise that can challenge well-established technical teams to provision hardware, configure environments, tune performance, maintain security, adhere to data governance requirements, manage software updates, and constantly monitor for system issues. Organizations interested in decreasing their time to value with a managed Pinot solution can take advantage of the expertise of StarTree’s team to accelerate setup, deploy an architecture ready for scale, and offload infrastructure maintenance.

Improving security with SOC 2, SSO, and RBAC

Critical enterprise security features can be challenging to implement in open source Pinot environments. With StarTree’s managed Pinot, role-based access control (RBAC) simplifies administration for Pinot and allows organizations to assign and monitor user access based on roles to enforce secure and efficient access to sensitive data. StarTree Cloud provides enterprise-grade security with SOC 2 compliance, enhanced encryption, and single sign-on (SSO) capabilities.

Using automated data ingestion at scale

The minion task framework is a native component of Pinot to offload computationally intensive tasks away from the other Pinot components to conserve resources for low-latency queries and support real-time stream ingestion. StarTree can handle larger volumes of data efficiently with highly scalable implementations of minion tasks and a minion auto scaling feature that eliminates unnecessary infrastructure costs during idle times, as seen in the below figure.

StarTree’s automatic data ingestion framework is ideal for enterprise workloads because it improves scalability and reduces the data maintenance complexity often found in open source Pinot deployments. StarTree supports a large number of managed connectors, which are used to maintain metadata about the source and ingest data seamlessly into the platform. The data is then modelled to help you organize and structure the data fetched from the selected data source into Pinot tables. Indexes are then configured to optimize query performance, as per the flow in the diagram below.

Tiered storage for real-time query processing

With open source Pinot, tiered storage can be used for deep storage like Amazon Simple Storage Service (Amazon S3) for backup but not query processing, because storage is tightly coupled with compute and requires manual configuration of tenants with different storage speeds and server specifications. In the following diagram, an Amazon S3 tier is defined for the data to be moved from tightly coupled SSD to cloud storage when the data is 30 days old.


On the other hand, StarTree transitions less-frequently accessed data to cost-effective storage like Amazon S3, while maintaining quick access to frequently accessed data. StarTree’s tiered storage enables automation for real-time query processing with index pinning, prefetching, and intelligent data movement between hot and cold storage, optimizing both performance and cost. StarTree’s sophisticated approach to tiered storage is highly flexible and reduces replication overhead by keeping a single copy in cloud storage, which prevents the limitations of compressed deep store copies, as you can see in the below diagram

Improving scalability with off-heap upserts

Companies like Amberdata benefit from StarTree’s upsert support to routinely upsert 350,000 events per second, with peak workloads reaching 1 million upserts per second. StarTree Cloud enhanced upsert functionality boosts efficiency, usability, and scalability through the implementation of off-heap upserts. Behind the scenes, Pinot servers manage specific upsert metadata to determine if a newly inserted record’s primary key was previously encountered and identifies the current segment holding it. As shown below, StarTree Cloud moves this off-heap, enabling a scalable cache of metadata as the on-heap memory restrictions are removed

Customer success stories using Pinot with StarTree for real-time analytics

The following customers highlight their success using Pinot for StarTree:

Flexible deployment options for StarTree Cloud

StarTree offers multiple deployment options, including a StarTree hosted software as a service (SaaS) or customer hosted SaaS. StarTree hosted SaaS is ideal for organizations interested in fully offloading the operational burden of infrastructure management, scaling, performance tuning, and security from their team so they can focus on analytics. StarTree’s customer hosted SaaS provides flexibility for customers interested in deploying the solution within their AWS environment or other platform of choice. This is suitable for organizations who require higher infrastructure management controls in their perimeter but still want the operational ease of a managed service.

Self-managed Pinot or StarTree

Pinot can deliver value for real-time analytics scenarios with different deployment methods. The choice of deployment method will come down to organizational priorities and trade-offs. Teams with the capability and willingness to manage open source software on a commodity infrastructure at scale might opt to deploy self-managed Pinot on AWS. Teams interested in reducing time troubleshooting performance bottlenecks, optimizing resource usage, and minimizing downtime can use StarTree’s managed service.

Conclusion

In this post, we presented StarTree as a managed solution on AWS for teams seeking the advantages of Apache Pinot. Like Pinot, StarTree addresses the need for a low-latency, high-concurrency, real-time online analytical processing (OLAP) solution. In addition, StarTree offers a managed experience for real-time and batch Pinot workloads, offering enhanced security, automated data ingestion, tiered storage, and off-heap upserts. These features improve security, scalability, and manageablity for organizations looking to run Pinot in production.

Developers interested in learning more about managed Pinot can deploy real-time analytics with StarTree to test it out or join a session with StarTree’s head of product. StarTree is an AWS ISVA partner and is available on AWS Marketplace.


About the Authors

Raj Ramasubbu is a Senior Analytics Specialist Solutions Architect focused on big data and analytics and AI/ML with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS. Raj provided technical expertise and leadership in building data engineering, big data analytics, business intelligence, and data science solutions for over 18 years prior to joining AWS. He helped customers in various industry verticals like healthcare, medical devices, life science, retail, asset management, car insurance, residential REIT, agriculture, title insurance, supply chain, document management, and real estate.

Francisco Morillo is a Streaming Solutions Architect at AWS. Francisco works with AWS customers, helping them design real-time analytics architectures using AWS services, supporting Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink.

Ismail Makhlouf is a Senior Specialist Solutions Architect for Data Analytics at AWS. Ismail focuses on architecting solutions for organizations across their end-to-end data analytics estate, including batch and real-time streaming, big data, data warehousing, and data lake workloads. He primarily partners with airlines, manufacturers, and retail organizations to support them to achieve their business objectives with well-architected data platforms.

Renee Berry is a Senior Partner Development Manager with the AWS Global Startup Program, working with venture backed startups partnering with AWS to scale their growth.

Mayank Shrivastava is a founding engineer of Apache Pinot and a PMC member for the project. He is currently a Fellow at StarTree Inc., where he also heads their Center of Excellence.

Barkha Herman is a technologist and developer advocate who founded WiTVoices and South Florida Women in Tech. She fosters inclusive tech communities.

Express brokers for Amazon MSK: Turbo-charged Kafka scaling with up to 20 times faster performance

Post Syndicated from Masudur Rahaman Sayem original https://aws.amazon.com/blogs/big-data/express-brokers-for-amazon-msk-turbo-charged-kafka-scaling-with-up-to-20-times-faster-performance/

Managing and scaling data streams efficiently is a cornerstone of success for many organizations. Apache Kafka has emerged as a leading platform for real-time data streaming, offering unmatched scalability and reliability. However, setting up and scaling Kafka clusters can be challenging, requiring significant time, expertise, and resources. This is where Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers come into play.

Express brokers are a new broker type in Amazon MSK that are designed to simplify Kafka deployment and scaling.

In this post, we walk you through the implementation of MSK Express brokers, highlighting their core features, benefits, and best practices for rapid Kafka scaling.

Key features of MSK Express brokers

MSK Express brokers revolutionize Kafka cluster management by delivering exceptional performance and operational simplicity. With up to three times more throughput per broker, Express brokers can sustainably handle an impressive 500 MBps ingress and 1000 MBps egress on m7g.16xl instances, setting new standards for data streaming performance.

Their standout feature is their fast scaling capability—up to 20 times faster than standard Kafka brokers—allowing rapid cluster expansion within minutes. This is complemented by 90% faster recovery from failures and built-in three-way replication, providing robust reliability for mission-critical applications.

Express brokers eliminate traditional storage management responsibility by offering unlimited storage without pre-provisioning, while simplifying operations through preconfigured best practices and automated cluster management. With full compatibility with existing Kafka APIs and comprehensive monitoring through Amazon CloudWatch and Prometheus, MSK Express brokers provide an ideal solution for organizations seeking a highly-performant and low-maintenance data streaming infrastructure.

Comparison with traditional Kafka deployment

Although Kafka provides robust fault-tolerance mechanisms, its traditional architecture, where brokers store data locally on attached storage volumes, can lead to several issues impacting the availability and resiliency of the cluster. The following diagram compares the deployment architecture.

Comparison with traditional Kafka deployment

The traditional architecture comes with the following limitations:

  • Extended recovery times – When a broker fails, recovery requires copying data from surviving replicas to the newly assigned broker. This replication process can be time-consuming, particularly for high-throughput workloads or in cases where recovery requires a new volume, resulting in extended recovery periods and reduced system availability.
  • Suboptimal load distribution – Kafka achieves load balancing by redistributing partitions across brokers. However, this rebalancing operation can strain system resources and take considerable time due to the volume of data that must be transferred between nodes.
  • Complex scaling operations – Expanding a Kafka cluster requires adding brokers and redistributing existing partitions across the new nodes. For large clusters with substantial data volumes, this scaling operation can impact performance and require significant time to complete.

MSK Express brokers offers fully managed and highly available Regional Kafka storage. This significantly decouples compute and storage resources, addressing the aforementioned challenges and improving the availability and resiliency of Kafka clusters. The benefits include:

  • Faster and more reliable broker recovery – When Express brokers recover, they do so in up to 90% less time than standard brokers and place negligible strain on the clusters’ resources, which makes recovery faster and more reliable.
  • Efficient load balancing – Load balancing in MSK Express brokers is faster and less resource-intensive, enabling more frequent and seamless load balancing operations.
  • Faster scaling – MSK Express brokers enable efficient cluster scaling through rapid broker addition, minimizing data transfer overhead and partition rebalancing time. New brokers become operational quickly due to accelerated catch-up processes, resulting in faster throughput improvements and minimal disruption during scaling operations.

Scaling use case example

Consider a use case requiring 300 MBps data ingestion on a Kafka topic. We implemented this using an MSK cluster with three m7g.4xlarge Express brokers. The configuration included a topic with 3,000 partitions and 24-hour data retention, with each broker initially managing 1,000 partitions.

To prepare for anticipated midday peak traffic, we needed to double the cluster capacity. This scenario highlights one of Express brokers’ key advantages: rapid, safe scaling without disrupting application traffic or requiring extensive advance planning. During this scenario, the cluster was actively handling approximately 300 MBps of ingestion. The following graph shows the total ingress on this cluster and the number of partitions it is holding across three brokers.

Scaling use case example

The scaling process involved two main steps:

  • Adding three additional brokers to the cluster, which completed in approximately 18 minutes
  • Using Cruise Control to redistribute the 3,000 partitions evenly across all six brokers, which took about 10 minutes

Scaling use case example

As shown in the following graph, the scaling operation completed smoothly, with partition rebalancing occurring rapidly across all six brokers while maintaining uninterrupted producer traffic.

Scaling use case example

Notably, throughout the entire process, we observed no disruption to producer traffic. The entire operation to double the cluster’s capacity was completed in just 28 minutes, demonstrating MSK Express brokers’ ability to scale efficiently with minimal impact on ongoing operations.

Best practices

Consider the following guidelines to adopt MSK Express brokers:

  • When implementing new streaming workloads on Kafka, select MSK Express brokers as your default option. If uncertain about your workload requirements, begin with express.m7g.large instances.
  • Use the Amazon MSK sizing tool to calculate optimal broker count and type for your workload. Although this provides a good baseline, always validate through load testing that simulates your real-world usage patterns.
  • Review and implement MSK Express broker best practices.
  • Choose larger instance types for high-throughput workloads. A smaller number of large instances is preferable to many smaller instances, because fewer total brokers can simplify cluster management operations and reduce operational overhead.

Conclusion

MSK Express brokers represent a significant advancement in Kafka deployment and management, offering a compelling solution for organizations seeking to modernize their data streaming infrastructure. Through its innovative architecture that decouples compute and storage, MSK Express brokers deliver simplified operations, superior performance, and rapid scaling capabilities.

The key advantages demonstrated throughout this post—including 3 times higher throughput, 20 times faster scaling, and 90% faster recovery times—make MSK Express brokers an attractive option for both new Kafka implementations and migrations from traditional deployments.

As organizations continue to face growing demands for real-time data processing, MSK Express brokers provide a future-proof solution that combines the reliability of Kafka with the operational simplicity of a fully managed service.

To get started, refer to Amazon MSK Express brokers.


About the Author

masudursMasudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.

Governing streaming data in Amazon DataZone with the Data Solutions Framework on AWS

Post Syndicated from Vincent Gromakowski original https://aws.amazon.com/blogs/big-data/governing-streaming-data-in-amazon-datazone-with-the-data-solutions-framework-on-aws/

Effective data governance has long been a critical priority for organizations seeking to maximize the value of their data assets. It encompasses the processes, policies, and practices an organization uses to manage its data resources. The key goals of data governance are to make data discoverable and usable by those who need it, accurate and consistent, secure and protected from unauthorized access or misuse, and compliant with relevant regulations and standards. Data governance involves establishing clear ownership and accountability for data, including defining roles, responsibilities, and decision-making authority related to data management.

Traditionally, data governance frameworks have been designed to manage data at rest—the structured and unstructured information stored in databases, data warehouses, and data lakes. Amazon DataZone is a data governance and catalog service from Amazon Web Services (AWS) that allows organizations to centrally discover, control, and evolve schemas for data at rest including AWS Glue tables on Amazon Simple Storage Service (Amazon S3), Amazon Redshift tables, and Amazon SageMaker models.

However, the rise of real-time data streams and streaming data applications impacts data governance, necessitating changes to existing frameworks and practices to effectively manage the new data dynamics. Governing these rapid, decentralized data streams presents a new set of challenges that extend beyond the capabilities of many conventional data governance approaches. Factors such as the ephemeral nature of streaming data, the need for real-time responsiveness, and the technical complexity of distributed data sources require a reimagining of how we think about data oversight and control.

In this post, we explore how AWS customers can extend Amazon DataZone to support streaming data such as Amazon Managed Streaming for Apache Kafka (Amazon MSK) topics. Developers and DevOps managers can use Amazon MSK, a popular streaming data service, to run Kafka applications and Kafka Connect connectors on AWS without becoming experts in operating it. We explain how they can use Amazon DataZone custom asset types and custom authorizers to: 1) catalog Amazon MSK topics, 2) provide useful metadata such as schema and lineage, and 3) securely share Amazon MSK topics across the organization. To accelerate the implementation of Amazon MSK governance in Amazon DataZone, we use the Data Solutions Framework on AWS (DSF), an opinionated open source framework that we announced earlier this year. DSF relies on AWS Cloud Development Kit (AWS CDK) and provides several AWS CDK L3 constructs that accelerate building data solutions on AWS, including streaming governance.

High-level approach for governing streaming data in Amazon DataZone

To anchor the discussion on supporting streaming data in Amazon DataZone, we use Amazon MSK as an integration example, but the approach and the architectural patterns remain the same for other streaming services (such as Amazon Kinesis Data Streams). At a high level, to integrate streaming data, you need the following capabilities:

  • A mechanism for the Kafka topic to be represented in the Amazon DataZone catalog for discoverability (including the schema of the data flowing inside the topic), tracking of lineage and other metadata, and for consumers to request access against.
  • A mechanism to handle the custom authorization flow when a consumer triggers the subscription grant to an environment. This flow consists of the following high-level steps:
    • Collect metadata of target Amazon MSK cluster or topic that’s being subscribed to by the consumer
    • Update the producer Amazon MSK cluster’s resource policy to allow access from the consumer role
    • Provide Kafka topic level AWS Identity and Access Management (IAM) permission to the consumer roles (more on this later) so that it has access to the target Amazon MSK cluster
    • Finally, update the internal metadata of Amazon DataZone so that it’s aware of the existing subscription between producer and consumer

Amazon DataZone catalog

Before you can represent the Kafka topic as an entry in the Amazon DataZone catalog, you need to define:

  1. A custom asset type that describes the metadata that’s needed to describe a Kafka topic. To describe the schema as part of the metadata, use the built-in form type amazon.datazone.RelationalTableFormType and create two more custom form types:
    1. MskSourceReferenceFormType that contains the cluster_ARN and the cluster_type. The type is used to determine whether the Amazon MSK cluster is provisioned or serverless, given that there’s a different process to grant consume permissions.
    1. KafkaSchemaFormType, which contains various metadata on the schema, including the kafka_topic, the schema_version, schema_arn, registry_arn, compatibility_mode (for example, backward-compatible or forward-compatible) and data_format (for example, Avro or JSON), which is helpful if you plan to integrate with the AWS Glue Schema registry.
  1. After the custom asset type has been defined, you can now create an asset based on the custom asset type. The asset describes the schema, the Amazon MSK cluster, and the topic that you want to be made discoverable and accessible to consumers.

Data source for Amazon MSK clusters with AWS Glue Schema registry

In Amazon DataZone, you can create data sources for AWS Glue Data Catalog to import technical metadata of database tables from AWS Glue and have the assets registered in the Amazon DataZone project. For importing metadata related to Amazon MSK, you need to use a custom data source, which can be an AWS Lambda function, using the Amazon DataZone APIs.

We provide as part of the solution a custom Amazon MSK data source with the AWS Glue Schema registry, for automating the creation, update, and deletion of custom Amazon MSK assets. It uses AWS Lambda to extract schema definitions from a Schema registry and metadata from the Amazon MSK clusters and then creates or updates the corresponding assets in Amazon DataZone.

Before explaining how the data source works, you need to know that every custom asset in Amazon DataZone has a unique identifier. When the data source creates an asset, it stores the asset’s unique identifier in Parameter Store, a capability of AWS Systems Manager.

The steps for how the data source works are as follows:

  1. The Amazon MSK AWS Glue Schema registry data source can be scheduled to be triggered on a given interval or by listening to AWS Glue Schema events such as Create, Update or Delete Schema. It can also be invoked manually through the AWS Lambda console.
  2. When triggered, it retrieves all the existing unique identifiers from Parameter Store. These parameters serve as reference to identify if an Amazon MSK asset already exists in Amazon DataZone.
  3. The function lists the Amazon MSK clusters and retrieves the Amazon Resource Name (ARN) for the given Amazon MSK name and additional metadata related to the Amazon MSK cluster type (serverless or provisioned). This metadata will be used later by the custom authorization flow.
  4. Then the function lists all the schemas in the Schema registry for a given registry name. For each schema, it retrieves the latest version and schema definition. The schema definition is what will allow you to add schema information when creating the asset in Amazon DataZone.
  5. For each schema retrieved in the Schema registry, the Lambda function checks if the assets already exist by looking into the Systems Manager parameters retrieved in the second step.
    1. If the asset exists, the Lambda function updates the asset in Amazon DataZone, creating a new revision with the updated schema or forms.
    2. If the asset doesn’t exist, the Lambda function creates the asset in Amazon DataZone and stores its unique identifier in Systems Manager for future reference.
  6. If there are schemas registered in Parameter Store that are no longer in the Schema registry, the data source deletes the corresponding Amazon DataZone assets and removes the associated parameters from Systems Manager.

The Amazon MSK AWS Glue Schema registry data source for Amazon DataZone enables seamless registration of Kafka topics as custom assets in Amazon DataZone. It does require that the topics in the Amazon MSK cluster are using the Schema registry for schema management.

Custom authorization flow

For managed assets such as AWS Glue Data Catalog and Amazon Redshift assets, the process to grant access to the consumer is managed by Amazon DataZone. Custom asset types are considered unmanaged assets, and the process to grant access needs to be implemented outside of Amazon DataZone.

The high-level steps for the end-to-end flow are as follows:

  1. (Conditional) If the consumer environment doesn’t have a subscription target, create it through the CreateSubscriptionTarget API call. The subscription target tells Amazon DataZone which environments are compatible with an asset type.
  2. The consumer triggers a subscription request by subscribing to the relevant streaming data asset through the Amazon DataZone portal.
  3. The producer receives the subscription request and approves (or denies) the request.
  4. After the subscription request has been approved by the producer, the consumer can observe the streaming data asset in their project under the Subscribed data section.
  5. The consumer can opt to trigger a subscription grant to a target environment directly from the Amazon DataZone portal, and this action triggers the custom authorization flow.

For steps 2–4, you rely on the default behavior of Amazon DataZone and no change is required. The focus of this section is then step 1 (subscription target) and step 5 (subscription grant process).

Subscription target

Amazon DataZone has a concept called environments within a project, which indicates where the resources are located and the related access configuration (for example, the IAM role) that is used to access those resources. To allow an environment to have access to the custom asset type, consumers have to use the Amazon DataZone CreateSubscriptionTarget API prior to the subscription grants. The creation of the subscription target is a one-time operation per custom asset type per environment. In addition, the authorizedPrincipals parameter inside the CreateSubscriptionTarget API lists the various IAM principals given access to the Amazon MSK topic as part of the grant authorization flow. Lastly, when calling CreateSubscriptionTarget, the underlying principle used to call the API must belong to the target environment’s AWS account ID.

After the subscription target has been created for a custom asset type and environment, the environment is eligible as a target for subscription grants.

Subscription grant process

Amazon DataZone emits events based on user actions, and you use this mechanism to trigger the custom authorization process when a subscription grant has been triggered for Amazon MSK topics. Specifically, you use the Subscription grant requested event. These are the steps of the authorization flow:

  1. A Lambda function collects metadata on the following:
    1. Producer Amazon MSK cluster or Kinesis data stream that the consumer is requesting access to. Metadata is collected using the GetListing API.
    2. Metadata about the target environment using a call to GetEnvironment API.
    3. Metadata about the subscription target using a call to GetSubscriptionTarget API to collect the consumer roles to grant.
    4. In parallel, Amazon DataZone internal metadata about the status of the subscription grant needs to be updated, and this happens in this step. Depending on the type of action that’s being done (such as GRANT or REVOKE), the status of the subscription grant is updated respectively (for example, GRANT_IN_PROGRESS, REVOKE_IN_PROGRESS).

After the metadata has been collected, it’s passed downstream as part of the AWS Step Functions state.

  1. Update the resource policy of the target resource (for example, Amazon MSK cluster or Kinesis data stream) in the producer account. The update allows authorized principals from the consumer to access or read the target resource. Example of the policy is as follows:
{
    "Effect": "Allow",
    "Principal": {
        "AWS": [
            "<CONSUMER_ROLES_ARN>"
        ]
    },
    "Action": [
        'kafka-cluster:Connect',
        'kafka-cluster:DescribeTopic',
        'kafka-cluster:DescribeGroup',
        'kafka-cluster:AlterGroup',
        'kafka-cluster:ReadData',
        "kafka:CreateVpcConnection",
        "kafka:GetBootstrapBrokers",
        "kafka:DescribeCluster",
        "kafka:DescribeClusterV2"
    ],
    "Resource": [
        "<CLUSTER_ARN>",
        "<TOPIC_ARN>",
        "<GROUP_ARN>"
    ]
}
  1. Update the configured authorized principals by attaching additional IAM permissions depending on specific scenarios. The following examples illustrate what’s being added.

The base access or read permissions are as follows:

{
    "Effect": "Allow",
    "Action": [
        'kafka-cluster:Connect',
        'kafka-cluster:DescribeTopic',
        'kafka-cluster:DescribeGroup',
        'kafka-cluster:AlterGroup',
        'kafka-cluster:ReadData'
    ],
    "Resource": [
        "<CLUSTER_ARN>",
        "<TOPIC_ARN>",
        "<GROUP_ARN>"
    ]
}

If there’s an AWS Glue Schema registry ARN provided as part of the AWS CDK construct parameter, then additional permissions are added to allow access to both the registry and the specific schema:

{
    "Effect": "Allow",
    "Action": [
        "glue:GetRegistry",
        "glue:ListRegistries",
        "glue:GetSchema",
        "glue:ListSchemas",
        "glue:GetSchemaByDefinition",
        "glue:GetSchemaVersion",
        "glue:ListSchemaVersions",
        "glue:GetSchemaVersionsDiff",
        "glue:CheckSchemaVersionValidity",
        "glue:QuerySchemaVersionMetadata",
        "glue:GetTags"
    ],
    "Resource": [
        "<REGISTRY_ARN>",
        "<SCHEMA_ARN>"
    ]
}

If this grant is for a consumer in a different account, the following permissions are also added to allow managed VPC connections to be created by the consumer:

{
    "Effect": "Allow",
    "Action": [
        "kafka:CreateVpcConnection",
        "ec2:CreateTags",
        "ec2:CreateVPCEndpoint"
    ],
    "Resource": "*"
}
  1. Update the Amazon DataZone internal metadata on the progress of the subscription grant (for example, GRANTED or REVOKED). If there’s an exception in a step, it’s handled inside Step Functions and the subscription grant metadata is updated with a failed state (for example, GRANT_FAILED or REVOKE_FAILED).

Because Amazon DataZone supports multi-account architecture, the subscription grant process is a distributed workflow that needs to perform actions across different accounts, and it’s orchestrated from the Amazon DataZone domain account where all the events are received.

Implement streaming governance in Amazon DataZone with DSF

In this section, we deploy an example to illustrate the solution using DSF on AWS, which provides all the required components to accelerate the implementation of the solution. We use the following CDK L3 constructs from DSF:

  • DataZoneMskAssetType creates the custom asset type representing an Amazon MSK topic in Amazon DataZone
  • DataZoneGsrMskDataSource automatically creates Amazon MSK topic assets in Amazon DataZone based on schema definitions in the Schema registry
  • DataZoneMskCentralAuthorizer and DataZoneMskEnvironmentAuthorizer implement the subscription grant process for Amazon MSK topics and IAM authentication

The following diagram is the architecture for the solution.

Overall solution

In this example, we use Python for the example code. DSF also supports TypeScript.

Deployment steps

Follow the steps in the data-solutions-framework-on-aws README to deploy the solution. You need to deploy the CDK stack first, then create the custom environment and redeploy the stack with additional information.

Verify the example is working

To verify the example is working, produce sample data using the Lambda function StreamingGovernanceStack-ProducerLambda. Follow these steps:

  1. Use the AWS Lambda console to test the Lambda function by running a sample test event. The event JSON should be empty. Save your test event and click Test.

AWS Lambda run test

  1. Producing test events will generate a new schema producer-data-product in the Schema registry. Check the schema is created from the AWS Glue console using the Data Catalog menu from the left and selecting Stream schema registries.

AWS Glue schema registry

  1. New data assets should be in the Amazon DataZone portal, under the PRODUCER project
  2. On the DATA tab, in the left navigation pane, select Inventory data, as shown in the following screenshot
  3. Select producer-data-product

Streaming data product

  1. Select the BUSINESS METADATA tab to view the business metadata, as shown in the following screenshot.

business metadata

  1. To view the schema, select the SCHEMA tab, as shown in the following screenshot

data product schema

  1. To view the lineage, select the LINEAGE tab
  2. To publish the asset, select PUBLISH ASSET, as shown in the following screenshot

asset publication 

Subscribe

To subscribe, follow these steps:

  1. Switch to the consumer project by selecting CONSUMER in the top left of the screen
  2. Select Browse Catalog
  3. Choose producer-data-product and choose SUBSCRIBE, as shown in the following screenshot

subscription

  1. Return to the PRODUCER project and choose producer-data-product, as shown in the following screenshot

subscription grant

  1. Choose APPROVE, as shown in the following screenshot

subscription grant approval

  1. Go to the AWS Identity and Access Management (IAM) console and search for the consumer role. In the role definition, you should see an IAM inline policy with permissions on the Amazon MSK cluster, the Kafka topic, the Kafka consumer group, the AWS Glue schema registry and the schema from the producer.

IAM consumer policy

  1. Now let’s switch to the consumer’s environment in the Amazon Managed Service for Apache Flink console and run the Flink application called flink-consumer using the Run button.

Flink consumer

  1. Go back to the Amazon DataZone portal, and confirm that the lineage under the CONSUMER project was updated and the new Flink job run node was added to the lineage graph, as shown in the following screenshot

lineage

Clean up

To clean up the resources you created as part of this walkthrough, follow these steps:

  1. Stop the Amazon Managed Streaming for Apache Flink job.
  2. Revoke the subscription grant from the Amazon DataZone console.
  3. Run cdk destroy in your local terminal to delete the stack. Because you marked the constructs with a RemovalPolicy.DESTROY and configured DSF to remove data on destroy, running cdk destroy or deleting the stack from the AWS CloudFormation console will clean up the provisioned resources.

Conclusion

In this post, we shared how you can integrate streaming data from Amazon MSK within Amazon DataZone to create a unified data governance framework that spans the entire data lifecycle, from the ingestion of streaming data to its storage and eventual consumption by diverse producers and consumers.

We also demonstrated how to use the AWS CDK and the DSF on AWS to quickly implement this solution using built-in best practices. In addition to the Amazon DataZone streaming governance, DSF supports other patterns, such as Spark data processing and Amazon Redshift data warehousing. Our roadmap is publicly available, and we look forward to your feature requests, contributions, and feedback. You can get started using DSF by following our Quick start guide.


About the Authors

Vincent GromakowskiVincent Gromakowski is a Principal Analytics Solutions Architect at AWS where he enjoys solving customers’ data challenges. He uses his strong expertise on analytics, distributed systems and resource orchestration platform to be a trusted technical advisor for AWS customers.

Francisco MorilloFrancisco Morillo is a Sr. Streaming Solutions Architect at AWS, specializing in real-time analytics architectures. With over five years in the streaming data space, Francisco has worked as a data analyst for startups and as a big data engineer for consultancies, building streaming data pipelines. He has deep expertise in Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink. Francisco collaborates closely with AWS customers to build scalable streaming data solutions and advanced streaming data lakes, ensuring seamless data processing and real-time insights.
Jan Michael Go TanJan Michael Go Tan is a Principal Solutions Architect for Amazon Web Services. He helps customers design scalable and innovative solutions with the AWS Cloud.

Sofia ZilbermanSofia Zilberman is a Sr. Analytics Specialist Solutions Architect at Amazon Web Services. She has a track record of 15 years of creating large-scale, distributed processing systems. She remains passionate about big data technologies and architecture trends, and is constantly on the lookout for functional and technological innovations.

Amazon Web Services named a Leader in the 2024 Gartner Magic Quadrant for Data Integration Tools

Post Syndicated from William Vambenepe original https://aws.amazon.com/blogs/big-data/amazon-web-services-named-a-leader-in-the-2024-gartner-magic-quadrant-for-data-integration-tools/

Amazon Web Services (AWS) has been recognized as a Leader in the 2024 Gartner Magic Quadrant for Data Integration Tools. We were positioned in the Challengers Quadrant in 2023.

This recognition, we feel, reflects our ongoing commitment to innovation and excellence in data integration, demonstrating our continued progress in providing comprehensive data management solutions.

The Gartner Magic Quadrant evaluates 20 data integration tool vendors based on two axes—Ability to Execute and Completeness of Vision. This evaluation, we feel, critically examines vendors’ capabilities to address key service needs, including data engineering, operational data integration, modern data architecture delivery, and enabling less-technical data integration across various deployment models.

Discover, prepare, and integrate all your data at any scale

AWS Glue is a fully managed, serverless data integration service that simplifies data preparation and transformation across diverse data sources. With its comprehensive suite of tools, AWS Glue allows users to build and manage data pipelines efficiently, without requiring extensive infrastructure management expertise.

Given the diverse data integration needs of customers, AWS offers a robust data integration system through multiple services including Amazon EMR, Amazon Athena, Amazon Managed Workflows for Apache Airflow (Amazon MWAA), Amazon Managed Streaming for Apache Kafka (MSK), Amazon Kinesis, and others. Many thousands of customers across various industries are using these services to transform, operationalize, and manage their data across data lakes and data warehouses.

We have embarked on a journey to unify the broad range of AWS data processing, analytics, and AI capabilities, starting with the announcement of Amazon SageMaker Unified Studio at re:Invent 2024. This includes the data integration capabilities mentioned above, with support for both structured and unstructured data. With an integrated experience for data workers, SageMaker Unified Studio provides an environment where users can collaborate and build faster. It supports model development, generative AI, data processing, and SQL analytics, all accelerated by Amazon Q Developer—our most capable generative AI assistant for software development. The Unified Studio provides unified access to all data sources, whether stored in data lakes, data warehouses, or third-party and federated sources, with robust governance and enterprise-grade security built-in.

Review the Gartner Magic Quadrant

Access a complimentary copy of the full report to see why Gartner positioned AWS as a Leader, and dive deep into the strengths and cautions of AWS. We believe our recognition as a Leader in the Gartner Magic Quadrant is a testament to delivering innovations for our customers.

MQ

Gartner does not endorse any vendor, product or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.

GARTNER is a registered trademark and service mark of Gartner and Magic Quadrant is a registered trademark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and are used herein with permission. All rights reserved. This graphic was published by Gartner, Inc. as part of a larger research document and should be evaluated in the context of the entire document. The Gartner document is available upon request from here.


About the authors

William Vambenepe is Director of Product Management at AWS, where he leads the Product Management, Solutions Engineering, and UX Design team for data processing services (Amazon EMR, AWS Glue, Athena, Amazon MWAA), SageMaker Unified Studio, and SageMaker Catalog. Prior to AWS, William worked at Google (6 years building and growing the Data and Analytics product portfolio for Google Cloud, and 5 years as Product Management Director for Google Search). He had previously held software engineering leadership roles at Oracle and HP. William holds an Engineering degree from Ecole Centrale Paris, a graduate Diploma in Computer Science from Cambridge University, and a Masters in Engineering Management from Stanford University.

Santosh Chandrachood has been with AWS for over 8 years and helped build, launch, and scale a variety of AWS services. Currently, Santosh is Director and service leader for Data Processing, managing Amazon EMR, Athena, AWS Glue, and Managed Workflows for Apache Airflow (Amazon MWAA). Santosh also led AWS Data Integration as the General Manager. Before joining AWS, Santosh lead engineering teams in networking, storage, and data infrastructure areas.

Migrate from Standard brokers to Express brokers in Amazon MSK using Amazon MSK Replicator

Post Syndicated from Subham Rakshit original https://aws.amazon.com/blogs/big-data/migrate-from-standard-brokers-to-express-brokers-in-amazon-msk-using-amazon-msk-replicator/

Amazon Managed Streaming for Apache Kafka (Amazon MSK) now offers a new broker type called Express brokers. It’s designed to deliver up to 3 times more throughput per broker, scale up to 20 times faster, and reduce recovery time by 90% compared to Standard brokers running Apache Kafka. Express brokers come preconfigured with Kafka best practices by default, support Kafka APIs, and provide the same low latency performance that Amazon MSK customers expect, so you can continue using existing client applications without any changes. Express brokers provide straightforward operations with hands-free storage management by offering unlimited storage without pre-provisioning, eliminating disk-related bottlenecks. To learn more about Express brokers, refer to Introducing Express brokers for Amazon MSK to deliver high throughput and faster scaling for your Kafka clusters.

Creating a new cluster with Express brokers is straightforward, as described in Amazon MSK Express brokers. However, if you have an existing MSK cluster, you need to migrate to a new Express based cluster. In this post, we discuss how you should plan and perform the migration to Express brokers for your existing MSK workloads on Standard brokers. Express brokers offer a different user experience and a different shared responsibility boundary, so using them on an existing cluster is not possible. However, you can use Amazon MSK Replicator to copy all data and metadata from your existing MSK cluster to a new cluster comprising of Express brokers.

MSK Replicator offers a built-in replication capability to seamlessly replicate data from one cluster to another. It automatically scales the underlying resources, so you can replicate data on demand without having to monitor or scale capacity. MSK Replicator also replicates Kafka metadata, including topic configurations, access control lists (ACLs), and consumer group offsets.

In the following sections, we discuss how to use MSK Replicator to replicate the data from a Standard broker MSK cluster to an Express broker MSK cluster and the steps involved in migrating the client applications from the old cluster to the new cluster.

Planning your migration

Migrating from Standard brokers to Express brokers requires thorough planning and careful consideration of various factors. In this section, we discuss key aspects to address during the planning phase.

Assessing the source cluster’s infrastructure and needs

It’s crucial to evaluate the capacity and health of the current (source) cluster to make sure it can handle additional consumption during migration, because MSK Replicator will retrieve data from the source cluster. Key checks include:

    • CPU utilization – The combined CPU User and CPU System utilization per broker should remain below 60%.
    • Network throughput – The cluster-to-cluster replication process adds extra egress traffic, because it might need to replicate the existing data based on business requirements along with the incoming data. For instance, if the ingress volume is X GB/day and data is retained in the cluster for 2 days, replicating the data from the earliest offset would cause the total egress volume for replication to be 2X GB. The cluster must accommodate this increased egress volume.

Let’s take an example where in your existing source cluster you have an average data ingress of 100 MBps and peak data ingress of 400 MBps with retention of 48 hours. Let’s assume you have one consumer of the data you produce to your Kafka cluster, which means that your egress traffic will be same compared to your ingress traffic. Based on this requirement, you can use the Amazon MSK sizing guide to calculate the broker capacity you need to safely handle this workload. In the spreadsheet, you will need to provide your average and maximum ingress/egress traffic in the cells, as shown in the following screenshot.

Because you need to replicate all the data produced in your Kafka cluster, the consumption will be higher than the regular workload. Taking this into account, your overall egress traffic will be at least twice the size of your ingress traffic.
However, when you run a replication tool, the resulting egress traffic will be higher than twice the ingress because you also need to replicate the existing data along with the new incoming data in the cluster. In the preceding example, you have an average ingress of 100 MBps and you retain data for 48 hours, which means that you have a total of approximately 18 TB of existing data in your source cluster that needs to be copied over on top of the new data that’s coming through. Let’s further assume that your goal for the replicator is to catch up in 30 hours. In this case, your replicator needs to copy data at 260 MBps (100 MBps for ingress traffic + 160 MBps (18 TB/30 hours) for existing data) to catch up in 30 hours. The following figure illustrates this process.

Therefore, in the sizing guide’s egress cells, you need to add an additional 260 MBps to your average data out and peak data out to estimate the size of the cluster you should provision to complete the replication safely and on time.

Replication tools act as a consumer to the source cluster, so there is a chance that this replication consumer can consume higher bandwidth, which can negatively impact the existing application client’s produce and consume requests. To control the replication consumer throughput, you can use a consumer-side Kafka quota in the source cluster to limit the replicator throughput. This makes sure that the replicator consumer will throttle when it goes beyond the limit, thereby safeguarding the other consumers. However, if the quota is set too low, the replication throughput will suffer and the replication might never end. Based on the preceding example, you can set a quota for the replicator to be at least 260 MBps, otherwise the replication will not finish in 30 hours.

  • Volume throughput – Data replication might involve reading from the earliest offset (based on business requirement), impacting your primary storage volume, which in this case is Amazon Elastic Block Store (Amazon EBS). The VolumeReadBytes and VolumeWriteBytes metrics should be checked to make sure the source cluster volume throughput has additional bandwidth to handle any additional read from the disk. Depending on the cluster size and replication data volume, you should provision storage throughput in the cluster. With provisioned storage throughput, you can increase the Amazon EBS throughput up to 1000 MBps depending on the broker size. The maximum volume throughput can be specified depending on broker size and type, as mentioned in Manage storage throughput for Standard brokers in a Amazon MSK cluster. Based on the preceding example, the replicator will start reading from the disk and the volume throughput of 260 MBps will be shared across all the brokers. However, existing consumers can lag, which will cause reading from the disk, thereby increasing the storage read throughput. Also, there is storage write throughput due to incoming data from the producer. In this scenario, enabling provisioned storage throughput will increase the overall EBS volume throughput (read + write) so that existing producer and consumer performance doesn’t get impacted due to the replicator reading data from EBS volumes.
  • Balanced partitions – Make sure partitions are well-distributed across brokers, with no skewed leader partitions.

Depending on the assessment, you might need to vertically scale up or horizontally scale out the source cluster before migration.

Assessing the target cluster’s infrastructure and needs

Use the same sizing tool to estimate the size of your Express broker cluster. Typically, fewer Express brokers might be needed compared to Standard brokers for the same workload because depending on the instance size, Express brokers allow up to three times more ingress throughput.

Configuring Express Brokers

Express brokers employ opinionated and optimized Kafka configurations, so it’s important to differentiate between configurations that are read-only and those that are read/write during planning. Read/write broker-level configurations should be configured separately as a pre-migration step in the target cluster. Although MSK Replicator will replicate most topic-level configurations, certain topic-level configurations are always set to default values in an Express cluster: replication-factor, min.insync.replicas, and unclean.leader.election.enable. If the default values differ from the source cluster, these configurations will be overridden.

As part of the metadata, MSK Replicator also copies certain ACL types, as mentioned in Metadata replication. It doesn’t explicitly copy the write ACLs except the deny ones. Therefore, if you’re using SASL/SCRAM or mTLS authentication with ACLs rather than AWS Identity and Access Management (IAM) authentication, write ACLs need to be explicitly created in the target cluster.

Client connectivity to the target cluster

Deployment of the target cluster can occur within the same virtual private cloud (VPC) or a different one. Consider any changes to client connectivity, including updates to security groups and IAM policies, during the planning phase.

Migration strategy: All at once vs. wave

Two migration strategies can be adopted:

  • All at once – All topics are replicated to the target cluster simultaneously, and all clients are migrated at once. Although this approach simplifies the process, it generates significant egress traffic and involves risks to multiple clients if issues arise. However, if there is any failure, you can roll back by redirecting the clients to use the source cluster. It’s recommended to perform the cutover during non-business hours and communicate with stakeholders beforehand.
  • Wave – Migration is broken into phases, moving a subset of clients (based on business requirements) in each wave. After each phase, the target cluster’s performance can be evaluated before proceeding. This reduces risks and builds confidence in the migration but requires meticulous planning, especially for large clusters with many microservices.

Each strategy has its pros and cons. Choose the one that aligns best with your business needs. For insights, refer to Goldman Sachs’ migration strategy to move from on-premises Kafka to Amazon MSK.

Cutover plan

Although MSK Replicator facilitates seamless data replication with minimal downtime, it’s essential to devise a clear cutover plan. This includes coordinating with stakeholders, stopping producers and consumers in the source cluster, and restarting them in the target cluster. If a failure occurs, you can roll back by redirecting the clients to use the source cluster.

Schema registry

When migrating from a Standard broker to an Express broker cluster, schema registry considerations remain unaffected. Clients can continue using existing schemas for both producing and consuming data with Amazon MSK.

Solution overview

In this setup, two Amazon MSK provisioned clusters are deployed: one with Standard brokers (source) and the other with Express brokers (target). Both clusters are located in the same AWS Region and VPC, with IAM authentication enabled. MSK Replicator is used to replicate topics, data, and configurations from the source cluster to the target cluster. The replicator is configured to maintain identical topic names across both clusters, providing seamless replication without requiring client-side changes.

During the first phase, the source MSK cluster handles client requests. Producers write to the clickstream topic in the source cluster, and a consumer group with the group ID clickstream-consumer reads from the same topic. The following diagram illustrates this architecture.

When data replication to the target MSK cluster is complete, we need to evaluate the health of the target cluster. After confirming the cluster is healthy, we need to migrate the clients in a controlled manner. First, we need to stop the producers, reconfigure them to write to the target cluster, and then restart them. Then, we need to stop the consumers after they have processed all remaining records in the source cluster, reconfigure them to read from the target cluster, and restart them. The following diagram illustrates the new architecture.

After verifying that all clients are functioning correctly with the target cluster using Express brokers, we can safely decommission the source MSK cluster with Standard brokers and the MSK Replicator.

Deployment Steps

In this section, we discuss the step-by-step process to replicate data from an MSK Standard broker cluster to an Express broker cluster using MSK Replicator and also the client migration strategy. For the purpose of the blog, “all at once” migration strategy is used.

Provision the MSK cluster

Download the AWS CloudFormation template to provision the MSK cluster. Deploy the following in us-east-1 with stack name as migration.

This will create the VPC, subnets, and two Amazon MSK provisioned clusters: one with Standard brokers (source) and another with Express brokers (target) within the VPC configured with IAM authentication. It will also create a Kafka client Amazon Elastic Compute Cloud (Amazon EC2) instance where from we can use the Kafka command line to create and view Kafka topics and produce and consume messages to and from the topic.

Configure the MSK client

On the Amazon EC2 console, connect to the EC2 instance named migration-KafkaClientInstance1 using Session Manager, a capability of AWS Systems Manager.

After you log in, you need to configure the source MSK cluster bootstrap address to create a topic and publish data to the cluster. You can get the bootstrap address for IAM authentication from the details page for the MSK cluster (migration-standard-broker-src-cluster) on the Amazon MSK console, under View Client Information. You also need to update the producer.properties and consumer.properties files to reflect the bootstrap address of the standard broker cluster.

sudo su - ec2-user

export BS_SRC=<<SOURCE_MSK_BOOTSTRAP_ADDRESS>>
sed -i "s/BOOTSTRAP_SERVERS_CONFIG=/BOOTSTRAP_SERVERS_CONFIG=${BS_SRC}/g" producer.properties 
sed -i "s/bootstrap.servers=/bootstrap.servers=${BS_SRC}/g" consumer.properties

Create a topic

Create a clickstream topic using the following commands:

/home/ec2-user/kafka/bin/kafka-topics.sh --bootstrap-server=$BS_SRC \
--create --replication-factor 3 --partitions 3 \
--topic clickstream \
--command-config=/home/ec2-user/kafka/config/client_iam.properties

Produce and consume messages to and from the topic

Run the clickstream producer to generate events in the clickstream topic:

cd /home/ec2-user/clickstream-producer-for-apache-kafka/

java -jar target/KafkaClickstreamClient-1.0-SNAPSHOT.jar -t clickstream \
-pfp /home/ec2-user/producer.properties -nt 8 -rf 3600 -iam \
-gsr -gsrr <<REGION>> -grn default-registry -gar

Open another Session Manager instance and from that shell, run the clickstream consumer to consume from the topic:

cd /home/ec2-user/clickstream-consumer-for-apache-kafka/

java -jar target/KafkaClickstreamConsumer-1.0-SNAPSHOT.jar -t clickstream \
-pfp /home/ec2-user/consumer.properties -nt 3 -rf 3600 -iam \
-gsr -gsrr <<REGION>> -grn default-registry

Keep the producer and consumer running. If not interrupted, the producer and consumer will run for 60 minutes before it exits. The -rf parameter controls how long the producer and consumer will run.

Create an MSK replicator

To create an MSK replicator, complete the following steps:

  1. On the Amazon MSK console, choose Replicators in the navigation pane.
  2. Choose Create replicator.
  3. In the Replicator details section, enter a name and optional description.

  1. In the Source cluster section, provide the following information:
    1. For Cluster region, choose us-east-1.
    2. For MSK cluster, enter the MSK cluster Amazon Resource Name (ARN) for the Standard broker.

After the source cluster is selected, it automatically selects the subnets associated with the primary cluster and the security group associated with the source cluster. You can also select additional security groups.

Make sure that the security groups have outbound rules to allow traffic to your cluster’s security groups. Also make sure that your cluster’s security groups have inbound rules that accept traffic from the replicator security groups provided here.

  1. In the Target cluster section, for MSK cluster¸ enter the MSK cluster ARN for the Express broker.

After the target cluster is selected, it automatically selects the subnets associated with the primary cluster and the security group associated with the source cluster. You can also select additional security groups.

Now let’s provide the replicator settings.

  1. In the Replicator settings section, provide the following information:
    1. For the purpose of the example, we have kept the topics to replicate as a default value that would replicate all topics from primary to secondary cluster.
    2. For Replicator starting position, we configure it to replicate from the earliest offset, so that we can get all the events from the start of the source topics.
    3. To configure the topic name in the secondary cluster as identical to the primary cluster, we select Keep the same topic names for Copy settings. This makes sure that the MSK clients don’t need to add a prefix to the topic names.

    1. For this example, we keep the Consumer Group Replication setting as default (make sure it’s enabled to allow redirected clients resume processing data from the last processed offset).
    2. We set Target Compression type as None.

The Amazon MSK console will automatically create the required IAM policies. If you’re deploying using the AWS Command Line Interface (AWS CLI), SDK, or AWS CloudFormation, you have to create the IAM policy and use it as per your deployment process.

  1. Choose Create to create the replicator.

The process will take around 15–20 minutes to deploy the replicator. When the MSK replicator is running, this will be reflected in the status.

Monitor replication

When the MSK replicator is up and running, monitor the MessageLag metric. This metric indicates how many messages are yet to be replicated from the source MSK cluster to the target MSK cluster. The MessageLag metric should come down to 0.

Migrate clients from source to target cluster

When the MessageLag metric reaches 0, it indicates that all messages have been replicated from the source MSK cluster to the target MSK cluster. At this stage, you can cut over client applications from the source to the target cluster. Before initiating this step, confirm the health of the target cluster by reviewing the Amazon MSK metrics in Amazon CloudWatch and making sure that the client applications are functioning properly. Then complete the following steps:

  1. Stop the producers writing data to the source (old) cluster with Standard brokers and reconfigure them to write to the target (new) cluster with Express brokers.
  2. Before migrating the consumers, make sure that the MaxOffsetLag metric for the consumers has dropped to 0, confirming that they have processed all existing data in the source cluster.
  3. When this condition is met, stop the consumers and reconfigure them to read from the target cluster.

The offset lag happens if the consumer is consuming slower than the rate the producer is producing data. The flat line in the following metric visualization shows that the producer has stopped producing to the source cluster while the consumer attached to it continues to consume the existing data and eventually consumes all the data, therefore the metric goes to 0.

  1. Now you can update the bootstrap address in properties and consumer.properties to point to the target Express based MSK cluster. You can get the bootstrap address for IAM authentication from the MSK cluster (migration-express-broker-dest-cluster) on the Amazon MSK console under View Client Information.
export BS_TGT=<<TARGET_MSK_BOOTSTRAP_ADDRESS>>
sed -i "s/BOOTSTRAP_SERVERS_CONFIG=.*/BOOTSTRAP_SERVERS_CONFIG=${BS_TGT}/g" producer.properties
sed -i "s/bootstrap.servers=.*/bootstrap.servers=${BS_TGT}/g" consumer.properties

  1. Run the clickstream producer to generate events in the clickstream topic:
cd /home/ec2-user/clickstream-producer-for-apache-kafka/

java -jar target/KafkaClickstreamClient-1.0-SNAPSHOT.jar -t clickstream \
-pfp /home/ec2-user/producer.properties -nt 8 -rf 60 -iam \
-gsr -gsrr <<REGION>> -grn default-registry -gar

  1. In another Session Manager instance and from that shell, run the clickstream consumer to consume from the topic:
cd /home/ec2-user/clickstream-consumer-for-apache-kafka/

java -jar target/KafkaClickstreamConsumer-1.0-SNAPSHOT.jar -t clickstream \
-pfp /home/ec2-user/consumer.properties -nt 3 -rf 60 -iam \
-gsr -gsrr <<REGION>> -grn default-registry

We can see that the producers and consumers are now producing and consuming to the target Express based MSK cluster. The producers and consumers will run for 60 seconds before they exit.

The following screenshot shows producer-produced messages to the new Express based MSK cluster for 60 seconds.

Migrate stateful applications

Stateful applications such as Kafka Streams, KSQL, Apache Spark, and Apache Flink use their own checkpointing mechanisms to store consumer offsets instead of relying on Kafka’s consumer group offset mechanism. When migrating topics from a source cluster to a target cluster, the Kafka offsets in the source will differ from those in the target. As a result, migrating a stateful application along with its state requires careful consideration, because the existing offsets are incompatible with the target cluster’s offsets. Before migrating stateful applications, it is crucial to stop producers and make sure that consumer applications have processed all data from the source MSK cluster.

Migrate Kafka Streams and KSQL applications

Kafka Streams and KSQL store consumer offsets in internal changelog topics. It is advisable not to replicate these internal changelog topics to the target MSK cluster. Instead, the Kafka Streams application should be configured to start from the earliest offset of the source topics in the target cluster. This allows the state to be rebuilt. However, this method results in duplicate processing, because all the data in the topic is reprocessed. Therefore, the target destination (such as a database) must be idempotent to handle these duplicates effectively.

Express brokers don’t allow configuring segment.bytes to optimize performance. Therefore, the internal topics need to be manually created before the Kafka Streams application is migrated to the new Express based cluster. For more information, refer to Using Kafka Streams with MSK Express brokers and MSK Serverless.

Migrate Spark applications

Spark stores offsets in its checkpoint location, which should be a file system compatible with HDFS, such as Amazon Simple Storage Service (Amazon S3). After migrating the Spark application to the target MSK cluster, you should remove the checkpoint location, causing the Spark application to lose its state. To rebuild the state, configure the Spark application to start processing from the earliest offset of the source topics in the target cluster. This will lead to re-processing all the data from the start of the topic and therefore will generate duplicate data. Consequently, the target destination (such as a database) must be idempotent to effectively handle these duplicates.

Migrate Flink applications

Flink stores consumer offsets within the state of its Kafka source operator. When checkpoints are completed, the Kafka source commits the current consuming offset to provide consistency between Flink’s checkpoint state and the offsets committed on Kafka brokers. Unlike other systems, Flink applications don’t rely on the __consumer_offsets topic to track offsets; instead, they use the offsets stored in Flink’s state.

During Flink application migration, one approach is to start the application without a Savepoint. This approach discards the entire state and reverts to reading from the last committed offset of the consumer group. However, this prevents the application from accurately rebuilding the state of downstream Flink operators, leading to discrepancies in computation results. To address this, you can either avoid replicating the consumer group of the Flink application or assign a new consumer group to the application when restarting it in the target cluster. Additionally, configure the application to start reading from the earliest offset of the source topics. This enables re-processing all data from the source topics and rebuilding the state. However, this method will result in duplicate data, so the target system (such as a database) must be idempotent to handle these duplicates effectively.

Alternatively, you can reset the state of the Kafka source operator. Flink uses operator IDs (UIDs) to map the state to specific operators. When restarting the application from a Savepoint, Flink matches the state to operators based on their assigned IDs. It is recommended to assign a unique ID to each operator to enable seamless state restoration from Savepoints. To reset the state of the Kafka source operator, change its operator ID. Passing the operator ID as a parameter in a configuration file can simplify this process. Restart the Flink application with parameter --allowNonRestoredState (if you are running self-managed Flink). This will reset only the state of the Kafka source operator, leaving other operator states unaffected. As a result, the Kafka source operator resumes from the last committed offset of the consumer group, avoiding full reprocessing and state rebuilding. Although this might still produce some duplicates in the output, it results in no data loss. This approach is applicable only when using the DataStream API to build Flink applications.

Conclusion

Migrating from a Standard broker MSK cluster to an Express broker MSK cluster using MSK Replicator provides a seamless, efficient transition with minimal downtime. By following the steps and strategies discussed in this post, you can take advantage of the high-performance, cost-effective benefits of Express brokers while maintaining data consistency and application uptime.

Ready to optimize your Kafka infrastructure? Start planning your migration to Amazon MSK Express brokers today and experience improved scalability, speed, and reliability. For more details, refer to the Amazon MSK Developer Guide.


About the Author

Subham Rakshit is a Senior Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build streaming architectures so they can get value from analyzing their streaming data. His two little daughters keep him occupied most of the time outside work, and he loves solving jigsaw puzzles with them. Connect with him on LinkedIn.

Serverless ICYMI Q4 2024

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/serverless-icymi-q4-2024/

Welcome to the 27th edition of the AWS Serverless ICYMI (in case you missed it) quarterly recap. At the end of a quarter, we share the most recent product launches, feature enhancements, blog posts, webinars, live streams, and other interesting things that you might have missed!

In case you missed our last ICYMI, check out what happened in Q2 here.

Calendar showing October through December 2024

2024 Q4 calender

Serverless at re:Invent 2024

AWS re:Invent 2024 had 60,000 in-person attendees and 400,000 online viewers for the keynotes. The conference delivered 1,900 sessions from 3,500 speakers and included 546 AWS service and feature announcements.

The serverless content consisted of two tracks: Serverless (SVS) and App Integration (API). These tracks included 70 unique sessions and attracted nearly 11,000 attendees. Serverlesspresso, the coffee shop powered by serverless technology, operated in two locations during the event: the Expo Hall and the certification lounge.

Crowd of people standing around the AWS reI:nvent expo hall waiting to order coffee at the Serverlesspresso booth.

Serverlesspresso booth in the expo hall

Videos are available on Serverless Land YouTube.

AWS Lambda and Amazon Elastic Container Service (Amazon ECS) 10-year anniversary.

AWS marked significant milestones in serverless computing, celebrating 10 years of AWS Lambda and Amazon ECS. Lambda now serves over 1.5 million monthly customers and processes tens of trillions of requests each month. Amazon ECS launches more than 2.4 billion container tasks weekly and is used by over 65% of new AWS container customers.

AWS is commemorating this anniversary with insights from AWS Serverless Heroes, product leads, principal engineers, and AWS leadership sharing their perspectives on serverless evolution and future directions. These stories and insights are available at https://aws.amazon.com/serverless/10th-anniversary/.

AWS Lambda

The AWS Lambda team has spent a significant amount of time improving the Lambda development experience. Several enhancements have been made in the console as well as the local development experience.

Screen capture of the new AWS Lambda console with Code-OSS

Code-OSS as the new AWS Lambda inline editor

Lambda has launched a significant upgrade to its console by integrating Code-OSS, the open-source version of Visual Studio Code, delivering a familiar development experience directly in the cloud. The new Lambda Code Editor supports viewing larger function packages up to 50 MB, features a split-screen interface for simultaneous code editing and testing, and includes built-in Amazon Q Developer AI assistance for real-time coding suggestions. This enhancement comes at no additional cost and prioritizes accessibility with features like screen reader support and keyboard navigation. The update bridges the gap between cloud and local development by simplifying the process of downloading function code and AWS SAM templates, ultimately providing developers with a more streamlined and familiar serverless development experience. Watch the video explaining the changes in detail.

Additionally, the Lambda console enhances developer experience with two new features: a built-in CloudWatch Metrics Insights dashboard that surfaces key function metrics, and CloudWatch Logs Live Tail support for real-time log streaming and analysis, enabling faster troubleshooting without leaving the Lambda environment.

Screen capture of the new top 10 functions in the new AWS Lambda console

Top 10 Functions

Lambda now supports native JSON structured logging for .NET managed runtime applications, improving log searchability and analysis capabilities without requiring manual configuration of logging libraries.

Lambda has expanded its runtime support by adding Python 3.13 and Node.js 22 as both managed runtimes and container base images, providing access to the latest language features and ensuring long-term support through October 2029 and April 2027, respectively.

Lambda SnapStart capability is now available for Python and .NET runtimes, delivering sub-second startup performance for latency-sensitive applications by caching initialized execution environments.

Diagram of how SnapStart works compared to not having SnapStart

SnapStart support comparison

New CloudWatch metrics for Lambda Event Source Mappings provide enhanced visibility into event processing states for Amazon Simple Queue Service (SQS), Amazon Kinesis, and Amazon DynamoDB event sources, helping customers monitor and troubleshoot event processing issues.

Lambda introduces Provisioned Mode for Kafka event source mappings, allowing customers to optimize throughput by configuring dedicated event polling resources for applications with stringent performance requirements.

Finally, Lambda introduces an enhanced local development experience through the AWS Toolkit for Visual Studio Code, streamlining the serverless application development workflow. The update features a new Application Builder interface that guides developers through environment setup, offers sample applications, and provides quick-action buttons for common tasks like build, deploy, and invoke operations. Developers can now efficiently iterate on their code with features such as configurable build settings, step-through debugging, and the ability to sync local changes quickly to the cloud or perform full deployments. The toolkit integrates with AWS Infrastructure Composer for visual application building and includes comprehensive local testing capabilities with shareable test events. This enhancement simplifies the Lambda development process by enabling developers to author, test, debug, and deploy serverless applications without leaving their preferred IDE environment.

Screen capture of the getting started experience for serverless in a local IDE

Local IDE getting started

Amazon ECS and AWS Fargate

AWS enhances observability for containerized applications with CloudWatch Application Signals for Amazon ECS, adding infrastructure metrics correlation to existing traces and logs monitoring, enabling operators to identify and resolve performance issues across their application stack.

Amazon ECS adds service revision and deployment history tracking, allowing customers to monitor changes, track ongoing deployments, and debug deployment failures for long-running applications deployed after October 25, 2024.

A graph explaining the flow for service order and history

Service revisions and deployment history

Amazon ECS expands testing capabilities by supporting network fault injection experiments on AWS Fargate through AWS Fault Injection Service, enabling developers to verify application resilience using six different types of fault injection actions, including network disruptions and resource stress testing.

Amazon EventBridge

Amazon EventBridge announces significant performance improvements, reducing end-to-end latency by up to 94% from 2,235ms to 129.33ms at P99, enabling faster event processing for time-sensitive applications like fraud detection and gaming.

Amazon EventBridge and AWS Step Functions now integrate with private APIs through AWS PrivateLink and Amazon VPC Lattice, enabling secure connectivity between cloud and on-premises applications without custom networking code.

Screen capture of the Amazon EventBridge create connection screen showing the new Private option

Connections to Private APIs

EventBridge API destinations introduces proactive OAuth token refresh for public and private authorization endpoints, helping prevent delays and errors by automatically refreshing tokens before expiration.

AWS Step Functions

AWS Step Functions introduces the ability to export workflows as CloudFormation or SAM templates directly from the AWS console, enabling repeatable provisioning across accounts. Developers can export and customize templates from existing workflows, and use AWS Infrastructure Composer to visually connect workflows with other AWS resources.

Step Functions also adds Variables and JSONata support to enhance workflow development. Variables allow data assignment and reference between states, simplifying payload management, while JSONata provides advanced data transformation capabilities, including date formatting and mathematical operations. These features reduce the need for custom code and intermediate states, making it easier to build distributed serverless applications. Watch the in depth video to learn more.

Screen capture of AWS Step Function workflow studio using JSONata and variables in an example

JSONata and variables

Amazon Kinesis

Amazon Kinesis introduces significant updates to its client libraries. The new Kinesis Client Library (KCL) 3.0 reduces compute costs by up to 33% through enhanced load balancing, while the Kinesis Producer Library (KPL) 1.0 improves performance and security. Both libraries now support AWS SDK for Java 2.x and eliminate dependencies on SDK for Java 1.x, enabling seamless upgrades without requiring application code changes.

Screen capture of CPU usage metrics

KCL 3.0 metrics

Amazon MQ

Amazon MQ adds support for AWS PrivateLink, enabling customers to access Amazon MQ API endpoints directly from their VPC through interface VPC endpoints, eliminating the need for internet access and providing enhanced security through AWS’s internal network infrastructure.

Amazon Finch

AWS announces general availability of Linux support for Finch, an open source container development tool that simplifies building, running, and publishing Linux containers across all major operating systems. The release includes support for the Finch Daemon with Docker API compatibility and is available through RPM packages for Amazon Linux 2 and Amazon Linux 2023.

Amazon Simple Queue Service (SQS)

Amazon SQS increases the in-flight message limit for FIFO queues from 20,000 to 120,000 messages, enabling higher concurrent message processing. This enhancement allows customers to scale their receivers and process up to six times more messages simultaneously, provided they have sufficient publish throughput.

Amazon Managed Streaming for Apache Kafka(Amazon MSK)

Amazon MSK now introduces Managed Streaming for Apache Flink blueprints to simplify real-time AI application development. The service enables vector-embedding generation through Amazon Bedrock, streamlining the integration of streaming data with generative AI models. Using a straightforward configuration process, users can generate and index vector embeddings in Amazon OpenSearch, while leveraging LangChain’s data chunking capabilities for enhanced data retrieval efficiency. The service handles all integration aspects between MSK, embedding models, and Amazon OpenSearch vector stores.

AWS Amplify

AWS Amplify launches the Amplify AI kit for Amazon Bedrock, providing fullstack developers with tools to integrate AI capabilities into web applications. The kit includes a customizable React UI component, secure Bedrock access, and context-sharing features, enabling developers to implement chat, search, and summarization functionalities without machine learning expertise.

AWS AppSync

AWS AppSync launches AppSync Events, enabling developers to broadcast real-time data to multiple subscribers through serverless WebSocket APIs. The service eliminates the need to build and manage WebSocket infrastructure while providing secure, scalable event broadcasting capabilities. Developers can create APIs that automatically scale and integrate with services like Amazon EventBridge. The system supports features such as channel namespaces, event handlers, and multiple authorization modes, and is available in all regions where AWS AppSync operates. Users only pay for API operations and real-time connection minutes used.

Screen capture from the AWS AppSync console to create a new Event API.

Creating an AppSunc Event API

Amazon API Gateway

Amazon API Gateway released a significant enhancement to Amazon API Gateway, enabling customers to manage private REST APIs using custom private DNS names. This highly requested feature allows API providers to use user-friendly domain names like private.example.com, while maintaining TLS encryption for security. The implementation process involves creating a private custom domain, configuring certificates through AWS Certificate Manager (ACM), mapping private APIs, and setting resource policies. The feature supports cross-account sharing through AWS Resource Access Manager (AWS RAM) and is now available in all AWS Regions, including AWS GovCloud (US).

Serverless blog posts

October

November

Serverless Office Hours

Image from YouTube from the latest four Serverless Office Hours

Serverless office hours videos

October

November

Still looking for more?

The Serverless landing page has more information. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.

You can also follow the Serverless Developer Advocacy team on X (formerly Twitter) to see the latest news, follow conversations, and interact with the team.

And finally, visit the Serverless Land  for all your serverless needs.

Automate topic provisioning and configuration using Terraform with Amazon MSK

Post Syndicated from Vijay Kardile original https://aws.amazon.com/blogs/big-data/automate-topic-provisioning-and-configuration-using-terraform-with-amazon-msk/

As organizations deploy Amazon Managed Streaming for Apache Kafka (Amazon MSK) clusters across multiple use cases, the manual management of topic configurations can be challenging. This can lead to several issues:

  • Inefficiency – Manual configuration is time-consuming and error-prone, especially for large deployments. Maintaining consistency across multiple configurations can be difficult. To avoid this, Kafka administrators often set the create.topics.enable property on brokers, which leads to cluster operation inefficiency.
  • Human error – Manual configuration increases the risk of mistakes that can disrupt data flow and impact applications relying on Amazon MSK.
  • Scalability challenges – Scaling an Amazon MSK environment with manual configuration is cumbersome. Adding new topics or modifying existing ones requires manual intervention, hindering agility.

These challenges highlight the need for a more automated and robust approach to MSK topic configuration management.

In this post, we address this problem by using Terraform to optimize the configuration of MSK topics. This solution supports both provisioned and serverless MSK clusters.

Solution overview

Customers want a better way to manage the overhead of topics and their configurations. Manually handling topic configurations can be cumbersome and error-prone, making it difficult to keep track of changes and updates.

To address these challenges, you can use Terraform, an infrastructure as code (IaC) tool by HashiCorp. Terraform allows you to manage and provision infrastructure declaratively. It uses human-readable configuration files written in HashiCorp Configuration Language (HCL) to define the desired state of infrastructure resources. These resources can span virtual machines, networks, databases, and a vast array of cloud provider-specific offerings.

Terraform offers a compelling solution to the challenges of manual Kafka topic configuration. Terraform allows you to define and manage your Kafka topics through code. This approach provides several key benefits:

  • Automation – Terraform automates the creation, modification, and deletion of MSK topics.
  • Consistency and repeatability – Terraform configurations provide consistent topic structures and settings across your entire Amazon MSK environment. This simplifies management and reduces the likelihood of configuration drift.
  • Scalability – Terraform enables you to provision and manage large numbers of MSK topics, facilitating the growth of your Amazon MSK environment.
  • Version control – Terraform configurations are stored in version control systems, allowing you to track changes, roll back if needed, and collaborate effectively on your Amazon MSK infrastructure.

By using Terraform for MSK topic configuration management, you can streamline your operations, minimize errors, and have a robust and scalable Amazon MSK environment.

In this post, we provide a comprehensive guide for using Terraform to manage Amazon MSK configurations. We explore the process of installing Terraform on Amazon Elastic Compute Cloud (Amazon EC2), defining and decentralizing topic configurations, and deploying and updating configurations in an automated manner.

Prerequisites

Before proceeding with the solution, make sure you have the following resources and access:

By making sure you have these prerequisites in place, you will be ready to streamline your topic configurations with Terraform.

Install Terraform on your client machine

When your cluster and client machine are ready, SSH to your client machine (Amazon EC2) and install Terraform.

  1. Run the following commands to install Terraform:
    sudo yum update -y
    sudo yum install -y yum-utils shadow-utils
    sudo yum-config-manager --add-repo https://rpm.releases.hashicorp.com/AmazonLinux/hashicorp.repo
    sudo yum -y install terraform

  2. Run the following command to check the installation:
    terraform -v
    

This indicates that Terraform installation is successful and you are ready to automate your MSK topic configuration.

Provision an MSK topic using Terraform

To provision the MSK topic, complete the following steps:

  1. Create a new file called main.tf and copy the following code into this file, replacing the BOOTSTRAP_SERVERS and AWS_REGION information with the details for your cluster. For instructions on retrieving the bootstrap_servers information for IAM authentication from your MSK cluster, see Getting the bootstrap brokers for an Amazon MSK cluster. This script is common for Amazon MSK provisioned and MSK Serverless.
    terraform {
    required_providers {
    kafka = {
    source = "Mongey/kafka" }}}
    provider "kafka" {
    bootstrap_servers = [{BOOTSTRAP_SERVERS}]
    tls_enabled       = true
    sasl_mechanism    = "aws-iam"
    sasl_aws_region   ={AWS_REGION}
    sasl_aws_profile  = "dev" }
    resource "kafka_topic" "sampleTopic" {
    name               = "sampleTopic"
    replication_factor = 1
    partitions         = 50 }

  2. Add IAM bootstrap servers endpoints in a comma separated list format:
    BOOTSTRAP_SERVERS = ["b-2.mskcluster…. ","b-3.mskcluster…. ","b-1.mskcluster…. "]

  3. Run the command terraform init to initialize Terraform and download the required providers.

The terraform init command initializes a working directory containing Terraform configuration files(main.tf). This is the first command that should be run after writing a new Terraform configuration.

  1. Run the command terraform plan to review the run plan.

This command shows the changes that Terraform will make to the infrastructure based on the provided configuration. This step is optional but is often used as a preview of the changes Terraform will make.

  1. If the plan looks correct, run the command terraform apply to apply the configuration.
  2. When prompted for confirmation before proceeding, enter yes.

The terraform apply command runs the actions proposed in a Terraform plan. Terraform will create the sampleTopic topic in your MSK cluster.

  1. After the terraform apply command is complete, verify the infrastructure has been created with the help of the kafka-topics.sh utility:
    kafka/bin/kafka-topics.sh 
    --bootstrap-server "b-1…..amazonaws.com:9098" 
    --command-config ./kafka/bin/client.properties  
    --list

You can use the kafka-toipcs.sh tool with the --list option to retrieve a list of topics associated with your MSK cluster. For more information, refer to the createtopic documentation.

Update the MSK topic configuration using Terraform

To update the MSK topic configuration, let’s assume we want to change the number of partitions from 50 to 10 on our topic. We need to perform the following steps:

  1. Verify the number of partitions on the topic using the --describe command:
    kafka/bin/kafka-topics.sh 
    --bootstrap-server "b-1…...amazonaws.com:9098" 
    --command-config ./kafka/bin/client.properties  
    --describe 
    --topic sampleTopic

This command will show 50 partitions on the sampleTopic topic.

  1. Modify the Terraform file main.tf and change the value of the partitions parameter to 10:
    resource "kafka_topic" "sampleTopic" {
    name               = " sampleTopic "
    replication_factor = 1
    partitions         = 10 }

  2. Run the command terraform plan to review the run plan.

  1. If the plan shows the changes, run the command terraform apply to apply the configuration.
  2. When prompted for confirmation before proceeding, enter yes.

Terraform will drop and recreate the sampleTopic topic with the changed configuration.

  1. Verify the changed number of partitions on the topic, ad rerun the --describe command:
    kafka/bin/kafka-topics.sh 
    --bootstrap-server "b-1…...amazonaws.com:9098" 
    --command-config ./kafka/bin/client.properties  
    --describe --topic sampleTopic

Now, this command will show 10 partitions on the sampleTopic topic.

Delete the MSK topic using Terraform

When you no longer need the infrastructure, you can remove all resources created by your Terraform file.

  1. Run the command terraform destroy to remove the topic.
  2. When prompted for confirmation before proceeding, enter yes.

Terraform will delete the sampleTopic topic from your MSK cluster.

  1. To verify, rerun the --list command:
    kafka/bin/kafka-topics.sh 
    --bootstrap-server "b-1…..amazonaws.com:9098" 
    --command-config ./kafka/bin/client.properties  
    --list

Now, this command will not show the sampleTopic topic.

Conclusion

In this post, we addressed the common challenges associated with manual MSK topic configuration management and presented a robust Terraform-based solution. Using Terraform for automated topic provisioning and configuration streamlines your processes, fosters scalability, and enhances flexibility. Additionally, it facilitates automated deployments and centralized management.

We encourage you to explore Terraform as a means to optimize Amazon MSK configurations and unlock further efficiencies within your streaming data pipelines.


About the author

Vijay Kardile is a Sr. Technical Account Manager with Enterprise Support, India. With over two decades of experience in IT Consulting and Engineering, he specializes in Analytics services, particularly Amazon EMR and Amazon MSK. He has empowered numerous enterprise clients by facilitating their adoption of various AWS services and offering expert guidance on attaining operational excellence.

Fitch Group achieves multi-Region resiliency for mission-critical Kafka infrastructure with Amazon MSK Replicator

Post Syndicated from Kalyan Janaki original https://aws.amazon.com/blogs/big-data/fitch-group-achieves-multi-region-resiliency-for-mission-critical-kafka-infrastructure-with-amazon-msk-replicator/

Real-time data streaming and event processing are critical components of modern distributed systems architectures. Apache Kafka has emerged as a leading platform for building real-time data pipelines and enabling asynchronous communication between microservices and applications. However, running and managing Kafka clusters at scale can be challenging, requiring specialized expertise and significant operational overhead.

Amazon Managed Streaming for Apache Kafka (Amazon MSK) is a fully managed service that allows you to build and run production Kafka applications. With Amazon MSK, you can rely on AWS to handle the heavy lifting of provisioning and managing Kafka clusters, while you focus on building innovative applications and real-time data processing pipelines.

In this post, we explore how Fitch Group, one of the top credit rating companies, used Amazon MSK and Amazon MSK Replicator to achieve multi-Region resiliency for their mission-critical Kafka infrastructure.

About Fitch Group and their need for multi-region resiliency

As a leading global financial information services provider, Fitch Group delivers vital credit and risk insights, robust data, and dynamic tools to champion more efficient, transparent financial markets. With employees in over 30 countries, Fitch Group’s culture of credibility, independence, and transparency is embedded throughout its structure, which includes Fitch Ratings, one of the world’s top three credit ratings agencies, and Fitch Solutions, a leading provider of insights, data, and analytics.

To stay competitive and efficient in the fast-paced financial industry, Fitch Group strategically adopted an event-driven microservices architecture. At the heart of this ecosystem lies Kafka, specifically Amazon MSK, which serves as the backbone for their data integration systems.

Fitch Group uses Kafka to enable applications to send ratings-related business events, facilitating automation within their ratings workflow systems and providing real-time or near real-time processing. This architectural choice has significantly reduced the time to market for end-user-facing systems like Fitch Ratings Pro and Fitch Group Ratings websites. Moreover, Kafka’s robust capabilities allow for seamless aggregation and distribution of data from many disparate systems through their data platform, enhancing data consistency, reliability, and accessibility across the organization.

Given the critical role that Kafka plays in Fitch Group architecture, providing robust disaster recovery (DR) mechanisms became paramount. Any disruption to their Kafka infrastructure could have significant repercussions on their ratings workflow automation, real-time processing, and end-user-facing systems, potentially exposing Fitch Group to regulatory, financial, and reputational risks.

To achieve the desired levels of resiliency, Fitch Group had the following key requirements:

  • Multi-Region deployment – Deploy MSK clusters across multiple AWS Regions to provide business continuity and maintain service availability during Regional or service events
  • Automated replication – Replicate Kafka data across Regions in near real time with minimal latency and data loss
  • Consistent topic namespaces – Maintain the same Kafka topic names and structures across source and destination clusters to minimize application changes
  • Rapid recovery – In the event of a failover, enable applications to seamlessly start consuming from the replicated cluster with minimal Recovery Time Objective (RTO) and Recovery Point Objective (RPO)

Solution overview

Fitch Group chose to implement their multi-Region Kafka deployment using Amazon MSK and MSK Replicator. MSK Replicator is a fully managed replication service that enables continuous, automated data replication between MSK clusters within the same Region or across different Regions. It supports replicating data between clusters with different configurations, including varying broker counts, storage volumes, and Kafka versions. Here’s how Fitch Group used MSK Replicator to achieve their multi-Region resiliency goals:

  • Deployed MSK clusters in two separate Regions, with the primary cluster in the main Region and the secondary cluster in a different Region for disaster recovery
  • Configured MSK Replicator to continuously replicate data from the primary cluster to the secondary cluster, maintaining the same topic names and structures across both clusters
  • Implemented application failover logic to automatically switch to consuming from the secondary cluster in case of a primary cluster unavailability, with minimal recovery time and data loss

The following diagram illustrates this architecture

Benefits achieved

By implementing Amazon MSK and MSK Replicator, Fitch Group realized several key benefits:

  • Enhanced disaster recovery – The multi-Region deployment provides business continuity even in the face of Regional or service events.
  • Simplified operations – The managed capability of MSK Replicator offloads the operational complexity of self-managing custom replication solutions, reducing the burden on Fitch Group’s IT team
  • Scalability – The solution can scale to handle varying data loads, making sure that DR capabilities grow alongside business needs
  • Minimal application changes – MSK Replicator supports replicating topics with the same name, which eliminates the need for consumer application modifications, reducing development effort and potential errors
  • Seamless failover and failback – Bidirectional replication capabilities enable quick switching of operations to the standby Region with minimal disruption, and straightforward reversion after the primary Region is restored
  • Improved testing capabilities – The setup facilitates regular DR exercises without impacting production systems, allowing Fitch Group to validate their DR plans consistently

Conclusion

By using Amazon MSK and MSK Replicator, Fitch Group has successfully implemented a highly resilient and scalable Kafka infrastructure that meets their stringent business continuity and disaster recovery requirements. This multi-Region deployment enables them to process mission-critical financial data at scale while providing minimal downtime and data loss in the event of service events or disasters. As Fitch Group continues to innovate and grow, their robust Kafka infrastructure provides a solid foundation for future expansion and the development of new data-driven services, ultimately enhancing their ability to deliver timely and accurate financial insights to their clients.


About the authors

Kalyan Janaki is Senior Big Data & Analytics Specialist with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS.

Venu Nemallikanti is the Enterprise Architect and Lead for Event Streaming at Fitch Group, a globally recognized financial information services provider operating in over 30 countries. His primary responsibilities include overseeing the architecture and implementation of event streaming solutions, ensuring the seamless integration and performance of systems that deliver credit ratings, research, data, and analytics to a worldwide clientele.

Chaitanya Shah is a Principal Technical Account Manager with AWS, based out of New York. He loves to code and actively contributes to the AWS solutions labs to help customers solve complex problems. He provides guidance to AWS customers on best practices for their Cloud migrations. He is also specialized in AWS data transfer and the data and analytics domain.

Oleg Chugaev is a Principal Solutions Architect and Serverless evangelist with 20+ years in IT, holding multiple AWS certifications. At AWS, he drives customers through their cloud transformation journeys by converting complex challenges into actionable roadmaps for both technical and business audiences.

Top 6 game changers from AWS that redefine streaming data

Post Syndicated from Sai Maddali original https://aws.amazon.com/blogs/big-data/top-6-game-changers-from-aws-that-redefine-streaming-data/

Recently, AWS introduced over 50 new capabilities across its streaming services, significantly enhancing performance, scale, and cost-efficiency. Some of these innovations have tripled performance, provided 20 times faster scaling, and reduced failure recovery times by up to 90%. We have made it nearly effortless for customers to bring real-time context to AI applications and lakehouses.

In this post, we discuss the top six game changers that will redefine AWS streaming data.

Amazon MSK Express brokers: Kafka reimagined for AWS

AWS offers Express brokers for Amazon Managed Streaming for Apache Kafka (Amazon MSK)—a transformative breakthrough for customers needing high-throughput Kafka clusters that scale faster and cost less. With Express brokers, we are reimagining Kafka’s compute and storage decoupling to unlock performance and elasticity benefits. Express brokers offer up to three times more throughput than a comparable standard Apache Kafka broker, virtually unlimited storage, instant storage scaling, compute scaling in minutes vs. hours, and 90% faster recovery from failures compared to standard Kafka brokers. Customers can provision capacity in minutes without complex calculations, benefit from preset Kafka configurations, and scale capacity in a few clicks. Express brokers provide the same low-latency performance as standard Kafka, are 100% native Kafka, and offer key Amazon MSK features. There are no storage limits per broker and you only pay for the storage you use. With Express brokers for Amazon MSK, enterprises can expand their Kafka usage to support even more mission-critical use cases, while keeping both operational overhead and overall infrastructure costs low.

Amazon Kinesis Data Streams On-Demand: Scaling new heights

Amazon Kinesis Data Streams On-Demand makes it uncomplicated for developers to stream gigabytes per second of data without managing capacity or servers. Developers can create a new on-demand data stream or convert an existing data stream to on-demand mode with a single click. Kinesis Data Streams On-Demand now automatically scales to 10 GBps of write throughput and 200 GBps of read throughput per stream, a fivefold increase. Customers will automatically get this fivefold increase in scale without the need to take any action.

Streaming data to Iceberg tables in lakehouses

Enterprises are embracing lakehouses and open table formats such as Apache Iceberg to unlock value from their data. Amazon Data Firehose now supports seamless integration with Iceberg tables on Amazon Simple Storage Service (Amazon S3). Customers can stream data into Iceberg tables in Amazon S3 without any management overhead. Data Firehose compacts small files, minimizing storage inefficiencies and enhancing read performance. Data Firehose also handles schema changes while in flight, to provide consistency across evolving datasets. Because Data Firehose is fully managed and serverless, it scales seamlessly to handle high throughput streaming workloads, providing reliable and fast delivery of data. This capability also makes it straightforward to stream data stored in MSK topics and Kinesis data streams into Iceberg tables, potentially eliminating the need for custom extract, transform, and load (ETL) pipelines. Customers can now bring the power of real-time data to Iceberg tables without any additional effort—a paradigm shift for businesses. Additionally, Kinesis Data Firehose serves as a versatile bridge to stream real-time data from MSK clusters and Kinesis Data Streams into the newly launched Amazon S3 Tables and Amazon SageMaker Lakehouse. This unified approach facilitates more effective data management and analysis, supporting data-driven decision-making across the enterprise.

Unlocking the value of data stored in databases with change replication to Iceberg tables

Delivering database changes into Iceberg tables is emerging as a common pattern. Now in public preview, Data Firehose supports capturing changes made in databases such as PostgreSQL and MySQL and replicating the updates to Iceberg tables on Amazon S3. The integration uses change data capture (CDC) to continuously deliver database updates, eliminating manual processes and reducing operational overhead. Data Firehose automates tasks such as schema alignment and partitioning, making sure tables are optimized for analytics. With this new capability, customers can streamline their end-to-end data pipeline, allowing them to continually feed fresh data into an Iceberg table without needing to build a custom data pipeline.

Real-time context to generative AI applications

Customers tell us how they want to gain insights from generative AI by being able to bring their data to large language models (LLMs). They want to bring data as it’s generated to pre-trained models for more accurate and up-to-date responses. Amazon MSK provides a blueprint that allows customers to combine the context from real-time data with the powerful LLMs on Amazon Bedrock to generate accurate, up-to-date AI responses without writing custom code. Developers can configure the blueprint to generate vector embeddings using Amazon Bedrock embedding models, then index those embeddings in Amazon OpenSearch Service for data captured and stored in MSK topics. Customers can also improve the efficiency of data retrieval using built-in support for data chunking techniques from LangChain, an open source library, supporting high-quality inputs for model ingestion.

More cost-effective and reliable stream processing

AWS offers the Kinesis Client Library (KCL), an open source library, that simplifies the development of stream processing applications with Kinesis Data Streams. With KCL 3.0, customers can reduce compute costs to process streaming data by up to 33% compared to previous KCL versions. KCL 3.0 introduces an enhanced load balancing algorithm that continuously monitors the resource utilization of the stream processing workers and automatically redistributes the load from over-utilized workers to underutilized workers. These changes also enhance scalability and the overall efficiency of processing large volumes of streaming data. We have also made improvements to our Amazon Managed Service for Apache Flink. We offer the latest Flink versions on Amazon Managed Service for Apache Flink for customers to benefit from the latest innovations. Customers can also upgrade their existing applications to use new Flink versions with a new in-place version upgrade feature. Amazon Managed Service for Apache Flink now offers per-second billing, so customers can run their Flink applications for a short period and only pay for what they use, down to the nearest second.

Conclusion

AWS has made new innovations in data streaming services, bringing compelling value to customers on performance, scalability, elasticity, and ease of use. These advancements empower businesses to use real-time data more effectively, which modernizes the way for the next generation of data-driven applications and analytics. It is still Day 1!


About the authors

Sai Maddali is a Senior Manager Product Management at AWS who leads the product team for Amazon MSK. He is passionate about understanding customer needs, and using technology to deliver services that empowers customers to build innovative applications. Besides work, he enjoys traveling, cooking, and running.

Bill Crew is a Senior Product Marketing Manager. He is the lead marketer for Streaming and Messaging Services at AWS. Including Amazon Managed Streaming for Apache Kafka (Amazon MSK), Amazon Managed Service for Apache Flink, Amazon Data Firehose, Amazon Kinesis Data Streams, Amazon Message Broker (Amazon MQ), Amazon Simple Queue Service (Amazon SQS), and Amazon Simple Notification Services (Amazon SNS). Besides work, he enjoys collecting vintage vinyl records.

How REA Group approaches Amazon MSK cluster capacity planning

Post Syndicated from Eunice Aguilar original https://aws.amazon.com/blogs/big-data/how-rea-group-approaches-amazon-msk-cluster-capacity-planning/

This post was written by Eunice Aguilar and Francisco Rodera from REA Group.

Enterprises that need to share and access large amounts of data across multiple domains and services need to build a cloud infrastructure that scales as need changes. REA Group, a digital business that specializes in real estate property, solved this problem using Amazon Managed Streaming for Apache Kafka (Amazon MSK) and a data streaming platform called Hydro.

REA Group’s team of more than 3,000 people is guided by our purpose: to change the way the world experiences property. We help people with all aspects of their property experience—not just buying, selling, and renting—through the richest content, data and insights, valuation estimates, and home financing solutions. We deliver unparalleled value to our customers, Australia’s real estate agents, by providing access to the largest and most engaged audience of property seekers.

To achieve this, the different technical products within the company regularly need to move data across domains and services efficiently and reliably.

Within the Data Platform team, we have built a data streaming platform called Hydro to provide this capability across the whole organization. Hydro is powered by Amazon MSK and other tools with which teams can move, transform, and publish data at low latency using event-driven architectures. This type of structure is foundational at REA for building microservices and timely data processing for real-time and batch use cases like time-sensitive outbound messaging, personalization, and machine learning (ML).

In this post, we share our approach to MSK cluster capacity planning.

The problem

Hydro manages a large-scale Amazon MSK infrastructure by providing configuration abstractions, allowing users to focus on delivering value to REA without the cognitive overhead of infrastructure management. As the use of Hydro grows within REA, it’s crucial to perform capacity planning to meet user demands while maintaining optimal performance and cost-efficiency.

Hydro uses provisioned MSK clusters in development and production environments. In each environment, Hydro manages a single MSK cluster that hosts multiple tenants with differing workload requirements. Proper capacity planning makes sure the clusters can handle high traffic and provide all users with the desired level of service.

Real-time streaming is a relatively new technology at REA. Many users aren’t yet familiar with Apache Kafka, and accurately assessing their workload requirements can be challenging. As the custodians of the Hydro platform, it’s our responsibility to find a way to perform capacity planning to proactively assess the impact of the user workloads on our clusters.

Goals

Capacity planning involves determining the appropriate size and configuration of the cluster based on current and projected workloads, as well as considering factors such as data replication, network bandwidth, and storage capacity.

Without proper capacity planning, Hydro clusters can become overwhelmed by high traffic and fail to provide users with the desired level of service. Therefore, it’s very important to us to invest time and resources into capacity planning to make sure Hydro clusters can deliver the performance and availability that modern applications require.

The capacity planning approach we follow for Hydro covers three main areas:

  • The models used for the calculation of current and estimated future capacity needs, including the attributes used as variables in them
  • The models used to assess the approximate expected capacity required for a new Hydro workload joining the platform
  • The tooling available to operators and custodians to assess the historical and current capacity consumption of the platform and, based on them, the available headroom

The following diagram shows the interaction of capacity usage and the precalculated maximum usage.

Although we don’t have this capability yet, the goal is to take this approach one step further in the future and predict the approximate resource depletion time, as shown in the following diagram.

To make sure our digital operations are resilient and efficient, we must maintain a comprehensive observability of our current capacity usage. This detailed oversight allows us not only to understand the performance limits of our existing infrastructure, but also to identify potential bottlenecks before they impact our services and users.

By proactively setting and monitoring well-understood thresholds, we can receive timely alerts and take necessary scaling actions. This approach makes sure our infrastructure can meet demand spikes without compromising on performance, ultimately supporting a seamless user experience and maintaining the integrity of our system.

Solution overview

The MSK clusters in Hydro are configured with a PER_TOPIC_PER_BROKER level of monitoring, which provides metrics at the broker and topic levels. These metrics help us determine the attributes of the cluster usage effectively.

However, it wouldn’t be wise to display an excessive number of metrics on our monitoring dashboards because that could lead to less clarity and slower insights on the cluster. It’s more valuable to choose the most relevant metrics for capacity planning rather than displaying numerous metrics.

Cluster usage attributes

Based on the Amazon MSK best practices guidelines, we have identified several key attributes to assess the health of the MSK cluster. These attributes include the following:

  • In/out throughput
  • CPU usage
  • Disk space usage
  • Memory usage
  • Producer and consumer latency
  • Producer and consumer throttling

For more information on right-sizing your clusters, see Best practices for right-sizing your Apache Kafka clusters to optimize performance and cost, Best practices for Standard brokers, Monitor CPU usage, Monitor disk space, and Monitor Apache Kafka memory.

The following table contains the detailed list of all the attributes we use for MSK cluster capacity planning in Hydro.

Attribute Name Attribute Type Units Comments
Bytes in Throughput Bytes per second Relies on the aggregate Amazon EC2 network, Amazon EBS network, and Amazon EBS storage throughput
Bytes out Throughput Bytes per second Relies on the aggregate Amazon EC2 network, Amazon EBS network, and Amazon EBS storage throughput
Consumer latency Latency Milliseconds High or unacceptable latency values usually indicate user experience degradation before reaching actual resource (for example, CPU and memory) depletion
CPU usage Capacity limits % CPU user + CPU system Should stay under 60%
Disk space usage Persistent storage Bytes Should stay under 85%
Memory usage Capacity limits % Memory in use Should stay under 60%
Producer latency Latency Milliseconds High or unacceptable sustained latency values usually indicate user experience degradation before reaching actual capacity limits or actual resource (for example, CPU or memory) depletion
Throttling Capacity limits Milliseconds, bytes, or messages High or unacceptable sustained throttling values indicate capacity limits are being reached before actual resource (for example, CPU or memory) depletion

By monitoring these attributes, we can quickly evaluate the performance of the clusters as we add more workloads to the platform. We then match these attributes to the relevant MSK metrics available.

Cluster capacity limits

During the initial capacity planning, our MSK clusters weren’t receiving enough traffic to provide us with a clear idea of their capacity limits. To address this, we used the AWS performance testing framework for Apache Kafka to evaluate the theoretical performance limits. We conducted performance and capacity tests on the test MSK clusters that had the same cluster configurations as our development and production clusters. We obtained a more comprehensive understanding of the cluster’s performance by conducting these various test scenarios. The following figure shows an example of a test cluster’s performance metrics.

To perform the tests within a specific time frame and budget, we focused on the test scenarios that could efficiently measure the cluster’s capacity. For instance, we conducted tests that involved sending high-throughput traffic to the cluster and creating topics with many partitions.

After every test, we collected the metrics of the test cluster and extracted the maximum values of the key cluster usage attributes. We then consolidated the results and determined the most appropriate limits of each attribute. The following screenshot shows an example of the exported test cluster’s performance metrics.

Capacity monitoring dashboards

As part of our platform management process, we conduct monthly operational reviews to maintain optimal performance. This involves analyzing an automated operational report that covers all the systems on the platform. During the review, we evaluate the service level objectives (SLOs) based on select service level indicators (SLIs) and assess the monitoring alerts triggered from the previous month. By doing so, we can identify any issues and take corrective actions.

To assist us in conducting the operational reviews and to provide us with an overview of the cluster’s usage, we developed a capacity monitoring dashboard, as shown in the following screenshot, for each environment. We built the dashboard as infrastructure as code (IaC) using the AWS Cloud Development Kit (AWS CDK). The dashboard is generated and managed automatically as a component of the platform infrastructure, along with the MSK cluster.

By defining the maximum capacity limits of the MSK cluster in a configuration file, the limits are automatically loaded into the capacity dashboard as annotations in the Amazon CloudWatch graph widgets. The capacity limits annotations are clearly visible and provide us with a view of the cluster’s capacity headroom based on usage.

We determined the capacity limits for throughput, latency, and throttling through the performance testing. Capacity limits of the other metrics, such as CPU, disk space, and memory, are based on the Amazon MSK best practices guidelines.

During the operational reviews, we proactively assess the capacity monitoring dashboards to determine if more capacity needs to be added to the cluster. This approach allows us to identify and address potential performance issues before they have a significant impact on user workloads. It’s a preventative measure rather than a reactive response to a performance degradation.

Preemptive CloudWatch alarms

We have implemented preemptive CloudWatch alarms in addition to the capacity monitoring dashboards. These alarms are configured to alert us before a specific capacity metric reaches its threshold, notifying us when the sustained value reaches 80% of the capacity limit. This method of monitoring enables us to take immediate action instead of waiting for our monthly review cadence.

Value added by our capacity planning approach

As operators of the Hydro platform, our approach to capacity planning has provided a consistent way to assess how far we are from the theoretical capacity limits of all our clusters, regardless of their configuration. Our capacity monitoring dashboards are a key observability instrument that we review on a regular basis; they’re also useful while troubleshooting performance issues. They help us quickly tell if capacity constraints could be a potential root cause of any ongoing issues. This means that we can use our current capacity planning approach and tooling both proactively or reactively, depending on the situation and need.

Another benefit of this approach is that we calculate the theoretical maximum usage values that a given cluster with a specific configuration can withstand from a separate cluster without impacting any actual users of the platform. We spin up short-lived MSK clusters through our AWS CDK based automation and perform capacity tests on them. We do this quite often to assess the impact, if any, that changes made to the cluster’s configurations have on the known capacity limits. According to our current feedback loop, if these newly calculated limits change from the previously known ones, they are used to automatically update our capacity dashboards and alarms in CloudWatch.

Future evolution

Hydro is a platform that is constantly improving with the introduction of new features. One of these features includes the ability to conveniently create Kafka client applications. To meet the increasing demand, it’s essential to stay ahead of capacity planning. Although the approach discussed here has served us well so far, it’s by no means the final stage , and there are capabilities that we need to extend and areas we need to improve on.

Multi-cluster architecture

To support critical workloads, we’re considering using a multi-cluster architecture using Amazon MSK, which would also affect our capacity planning. In the future, we plan to profile workloads based on metadata, cross-check them with capacity metrics, and place them in the appropriate MSK cluster. In addition to the existing provisioned MSK clusters, we will evaluate how the Amazon MSK Serverless cluster type can complement our platform architecture.

Usage trends

We have added CloudWatch anomaly detection graphs to our capacity monitoring dashboards to track any unusual trends. However, because the CloudWatch anomaly detection algorithm only evaluates up to 2 weeks of metric data, we will reassess its usefulness as we onboard more workloads. Aside from identifying usage trends, we will explore options to implement an algorithm with predictive capabilities to detect when MSK cluster resources degrade and deplete.

Conclusion

Initial capacity planning lays a solid foundation for future improvements and provides a safe onboarding process for workloads. To achieve optimal performance of our platform, we must make sure that our capacity planning strategy evolves in line with the platform’s growth. As a result, we maintain a close collaboration with AWS to continually develop additional features that meet our business needs and are in sync with the Amazon MSK roadmap. This makes sure we stay ahead of the curve and can deliver the best possible experience to our users.

We recommend all Amazon MSK users not miss out on maximizing their cluster’s potential and to start planning their capacity. Implementing the strategies listed in this post is a great first step and will lead to smoother operations and significant savings in the long run.


About the Authors

Eunice Aguilar is a Staff Data Engineer at REA. She has worked in software engineering in various industries throughout the years and recently for property data. She’s also an advocate for women interested in transitioning into tech, along with the well-versed who she takes inspiration from.

Francisco Rodera is a Staff Systems Engineer at REA. He has extensive experience building and operating large-scale distributed systems. His interests are automation, observability, and applying SRE practices to business-critical services and platforms.

Khizer Naeem is a Technical Account Manager at AWS. He specializes in Efficient Compute and has a deep passion for Linux and open-source technologies, which he leverages to help enterprise customers modernize and optimize their cloud workloads.

Introducing Provisioned Mode for Kafka Event Source Mappings with AWS Lambda

Post Syndicated from Chris McPeek original https://aws.amazon.com/blogs/compute/introducing-provisioned-mode-for-kafka-event-source-mappings-with-aws-lambda/

This post is written by Tarun Rai Madan, Principal Product Manager, Serverless Compute and Rajesh Kumar Pandey, Principal Software Engineer, Serverless Compute

AWS is announcing the general availability of Provisioned Mode for AWS Lambda Event Source Mappings (ESMs) that subscribe to Apache Kafka event sources including Amazon MSK and self-managed Kafka. Provisioned Mode allows you to optimize the throughput of your Kafka ESM by provisioning event polling resources that remain ready to handle sudden spikes in traffic. Controlling the throughput of your ESM helps you build highly responsive and scalable event-driven Kafka applications with stringent performance requirements.

Overview

When you build modern applications using Event-Driven Architectures (EDAs), your event producers publish events, which are then processed by event source connectors like an ESM, and routed to serverless compute consumers like Lambda functions. Apache Kafka is a popular open-source platform for building real-time streaming data applications using Lambda functions as consumers. AWS Lambda’s fully-managed MSK ESM or self-managed Kafka ESM reads events from Kafka as an event source, performs operations like filtering and batching, and invokes Lambda functions. Both ESMs offer built-in integrations with event sources, auto-scaling, and features like batching and filtering. When a Kafka ESM is created, Lambda ESM allocates one event poller to start polling for messages in a Kafka topic. The ESM then evaluates the message backlog – using the OffsetLag metric – for all partitions in the topic, and auto-scales event pollers to process messages efficiently.

Many real-time applications using Kafka are sensitive to sudden spikes in traffic, which could lead to noticeable delays in your end users’ experience. Previously, there were no controls to optimize the throughput for performance-sensitive workloads when using Kafka ESMs. This forced you to explore alternative solutions for workloads with strict performance requirements, which added architectural complexity. To harness the power of Lambda for such performance-sensitive applications, you need to be able to control your Kafka ESM’s throughput and ensure responsive auto-scaling behavior.

What’s new

Provisioned Mode for ESM is a feature that helps you control the throughput of your ESM, and achieve an enhanced performance profile for performance-sensitive applications, particularly ones that see sudden spikes in traffic. You can use Provisioned Mode for Kafka ESM with a range of Kafka or Kafka-compatible streaming data platform providers like Amazon MSK, Confluent, Redpanda, and self-managed Kafka. Key benefits include:

  1. Controls to optimize throughput: You can now fine-tune the throughput of your ESM by configuring a minimum and maximum number of resources called “event pollers”. An event poller (or a “poller”) represents a compute resource that underpins an ESM in the Provisioned Mode, and allocates up to 5 MB/s throughput.
  2. Responsive auto-scaling: With Provisioned Mode, your Kafka ESM detects the increase in OffsetLag metric for all partitions in your Kafka topic, and auto-scales event pollers in a responsive manner. During idle periods, your ESM automatically scales down to the minimum event pollers set by you.
  3. Simplified networking experience and charges: Previously, you were required to configure AWS PrivateLink or NAT Gateway to enable Lambda to poll messages from Kafka clusters in your VPC and invoke Lambda functions. With Provisioned Mode, you are no longer required to configure PrivateLink or NAT Gateway. This approach reduces overhead and improves the developer experience, allowing you to focus on building applications rather than managing networking setup. Consequently, you are not charged for PrivateLink VPC endpoints when using Kafka as an event source with Lambda in the Provisioned Mode for ESM, which reduces your networking charges.

Activating Provisioned Mode for ESM

To activate Provisioned Mode for a new or existing Kafka ESM, you can configure the minimum event pollers, the maximum event pollers, or both for your ESM. The allowed values range from 1 to 200 for minimum event pollers, and from 1 to 2000 for maximum event pollers.

Note that you must configure at least one of minimum or maximum event pollers to activate Provisioned Mode. When you configure only the minimum number of event pollers (‘Min-only’), your ESM allocates this minimum quantity and can dynamically scale up to a maximum. This maximum is determined by the OffsetLag and is limited by either the number of partitions or the default maximum event pollers, whichever is lower. When you configure only the maximum number of event pollers (“Max-only”), your ESM starts with one minimum poller by default, and can scale up to the maximum event pollers or number of partitions, whichever is lower. When you configure both the minimum and maximum number of event pollers (“Min and Max”), your ESM can auto-scale between this range of minimum and maximum event pollers configured.

Activating using AWS CLI

You can activate Provisioned Mode for ESM during creation of a new ESM, or by updating an existing ESM. Specify the –provisioned-poller-config parameter.

aws lambda create-event-source-mapping \
    --region <region-name> \
    --function-name <function-name> \
    --event-source-arn <event-source-arn> \
    --provisioned-poller-config '{"MinimumPollers":<number>, "MaximumPollers":<number>}'

Activating using AWS Lambda Console

Select Configure provisioned mode to activate Provisioned Mode when creating a new ESM, or updating an existing one.

Image of Activating Provisioned Mode for ESM in Console.Figure 1: Activating Provisioned Mode for ESM in Console

Provisioned Mode for Kafka ESM in action

To see the performance profile with Provisioned Mode for Kafka ESM, deploy a Lambda function that subscribes to an Amazon MSK topic. Use the reference pattern on Serverless Land and see this blog post outlining steps to configure MSK ESM for a Lambda function. In this case, a producer writes 20 million messages, each with 1KB payload size to an MSK topic – distributed evenly across 100 partitions. Use a batch size of 100, with function duration at 100ms, and set the StartingPosition to TRIM_HORIZON to process from the beginning of the stream.

Note the baseline performance profile observed with the default On-Demand mode. Then analyze two configurations with the Provisioned Mode activated.

  • Scenario 1 uses different configurations for minimum event pollers
  • Scenario 2 uses the default minimum event pollers and lets Lambda manage the event pollers through autoscaling.

Baseline performance profile for Kafka ESM On-demand

With Provisioned Mode disabled, Lambda takes approximately 20 minutes to drain the backlog of 20 million messages. It takes 4 minutes to reach the maximum concurrent executions. Use this result as a baseline to compare against Provisioned Mode for ESM.

Image of Baseline performance without Provisioned Mode for ESM.

Figure 2: Baseline performance without Provisioned Mode for ESM

Scenario 1: Configuring minimum event pollers, and auto-scaling

To optimize the ESM throughput for this workload and reduce the time to drain the message backlog, configure the minimum event pollers. Select values of 10 and 100 for minimum event pollers, and observe the results.

Configuring 10 minimum event pollers

Lambda drains the backlog of 20 million messages in approximately 11 minutes with minimum pollers set to 10. This is 45% faster than the baseline without Provisioned Mode. It takes approximately 6 minutes to reach maximum concurrent executions.

Image of Performance profile with minimum event pollers set to 10.

Figure 3: Performance profile with minimum event pollers set to 10

Configuring 100 minimum event pollers

To further improve the processing performance, configure the minimum event pollers to 100. Lambda now takes 6 minutes to drain the backlog of 20 million messages, which is 70% faster than the baseline. It instantly reaches the maximum concurrent executions.

Image of Performance profile with minimum event pollers set to 100.

Figure 4: Performance profile with minimum event pollers set to 100

Scenario 2: Default minimum event pollers, and auto-scaling

In some cases, the workload may not be as performance-sensitive. With the same volume of 20M messages in your Kafka topic, activate Provisioned Mode for ESM. Start with the default minimum event pollers (set to 1) and let Lambda auto-scale the event pollers based on incoming traffic.

Lambda automatically scales up your event pollers to process the incoming messages, and scales them down as the backlog is cleared. With the default minimum and maximum event pollers, Lambda takes approximately 12 minutes to clear the backlog of 20 million messages, which is 40% faster than the baseline. Lambda takes 7 minutes to reach maximum concurrent executions.

Image of Performance profile with minimum event pollers set to 1.

Figure 5: Performance profile with minimum event pollers set to 1

The following table summarizes the performance improvement for the analyzed workload using Provisioned Mode for ESM.

ESM Mode Time to drain message backlog Percentage improvement
On-demand Mode 20 minutes Baseline
Provisioned Mode: Scenario 1 (fine-tuned minimum event pollers)
Minimum event pollers = 10 11 minutes 45%
Minimum event pollers = 100 6 minutes 70%
Provisioned Mode: Scenario 2 (default minimum event pollers)
Minimum event pollers = 1 12 minutes 40%

Table: Performance profile for reference test case before and after activating Provisioned Mode for ESM

Observability and Pricing

You can observe the usage of event pollers by monitoring the ProvisionedPollers Amazon CloudWatch metric, which measures the number of event pollers that actively processed at least one event in the last 5-minute window.

Pricing is based on the provisioned minimum event pollers and the number of event pollers consumed during automatic scaling. Provisioned Mode introduces a billing unit called Event Poller Unit (EPU). Each EPU supports up to 20 MB/s of throughput for event polling. The number of event pollers allocated on an EPU depends on the throughput consumed by each event poller. You pay for the number of EPUs used and the duration they run for, measured in Event Poller Unit hours. For details, refer to AWS Lambda pricing.

Best practices and considerations

The optimal configuration of minimum and maximum event pollers for your Kafka Event Source Mapping (ESM) depends on your application’s performance requirements. Start with the default minimum event pollers to baseline the performance profile, and adjust event pollers based on observed message processing patterns and your application’s performance requirements. For workloads with spiky traffic and strict performance needs, increase the minimum event pollers to handle sudden surges. You can fine-tune the minimum required event pollers by evaluating your desired throughput, your observed throughput – which depends on factors like the ingested messages per second and average payload size, and using the throughput capacity of one event poller (up to 5 MB/s) as reference. Note that to maintain ordered processing within a partition, Lambda caps the maximum event pollers at the number of partitions in the topic.

Update your network settings to remove PrivateLink VPC endpoints and associated permissions for existing ESMs when you activate Provisioned Mode.

Conclusion

Provisioned Mode for Lambda ESM allows you to fine-tune the throughput for your Kafka ESMs by configuring a minimum and maximum number of event pollers. This provides a responsive auto-scaling behavior for Kafka applications that have stringent performance requirements and see unpredictable and spiky traffic. You can fine-tune your configured event pollers based on your requirements and monitor usage via CloudWatch metrics. Provisioned Mode also simplifies network configuration by removing the requirement to configure PrivateLink.

For more serverless learning resources, visit Serverless Land.

The serverless attendee’s guide to AWS re:Invent 2024

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/the-serverless-attendees-guide-to-aws-reinvent-2024/

AWS re:Invent 2024 offers an extensive selection of serverless and application integration content.

AWS re:Invent Banner

AWS re:Invent Banner

For detailed descriptions and schedule, visit the AWS re:Invent Session Catalog.

Join AWS serverless experts and community members at the AWS Modern Apps and Open Source Zone in the AWS Expo Village. This serves as a hub for serverless discussions at re:Invent. While you are there, enjoy a free coffee and learn about serverless architectures at the Serverlesspresso booth. There are two this year, another one at the Certificate Lounge. The AWS Expo Village also includes Serverless and Serverless Containers booths.

Don’t have a ticket yet? Join us in Las Vegas from November 28-December 2, 2022 by registering for re:Invent 2024.

This guide organizes the sessions into categories to help you find the content this is most relevant to you.

Session Types

  • Breakout Sessions are lecture-style presentations covering architecture, best practices, and deep dives into AWS services.
  • Workshops are 2-hour hands-on sessions where you work through tasks in AWS accounts using AWS services. Laptops are required and AWS credits are provided.
  • Chalk Talks are highly interactive 60-minute sessions with smaller audiences, focused on technical deep dives with whiteboards for architectural discussions.
  • Builders’ Sessions are 60-minute small-group sessions led by an AWS expert who guides you through a technical problem using AWS services.
  • Code Talks are 60-minute live coding sessions where AWS experts show how to build solutions using AWS services.

Leadership session: Nick Coult, Usman Khalid, Kathleen deValk

  • SVS211: Celebrating 10 years of pioneering serverless and containers – Breakout.
    • Explore how serverless has evolved to help organizations drive the highest performance, availability, and security at low costs.

Getting started sessions

Are you new to serverless or taking your first steps? Hear from AWS experts and customers on best practices and strategies for building serverless workloads. Get hands-on with services by attending a workshop or builders session. Create the next great “to do” app or add a new customer experience for a theme park.

  • SVS202: Thinking serverless – Chalk Talk
    • Learn how to approach building solutions with a serverless mindset by breaking down business problems into serverless building blocks.
  • SVS205: Building a serverless web application for a theme park – Workshop
    • Learn how to build a complete serverless web application for a theme park called Innovator Island.
  • SVS201: Getting started with serverless patterns – Workshop
    • Learn how to recognize and apply common serverless patterns by building production-ready code for a serverless application.
  • SVS204: Write less code: Building applications with a serverless mindset – Builders Session
    • Get more value by using built-in integrations between AWS services through configuration rather than writing glue code.
  • SVS207: Effectively model costs for your serverless applications – Chalk Talk
    • Gain insights into modeling the cost of serverless applications on AWS by considering request loads, payload sizes, and service pricing.
  • API201: The AWS Step Functions workshop – Workshop
    • Learn about the features of AWS Step Functions through hands-on interactive modules.
  • API204: Building event-driven architectures – Workshop
    • Learn about the basics of event-driven design using examples involving Amazon SNS, Amazon SQS, AWS Lambda, Amazon EventBridge, and more.
  • API205: Unlock the power of an exceptional serverless developer experience – Code Talk
    • Learn how to accelerate your serverless development with AWS tools, including Amazon Q Developer integrated into IDEs.
  • SEG209: Getting started building serverless SaaS architectures
    • Discover how to build your first serverless application, and learn how to handle multi-tenant architectures for SaaS applications.

Understanding serverless architectures

  • SVS208: Balance consistency and developer freedom with platform engineering – Breakout
    • Learn how platform teams can provide opinionated security, cost, observability, reliability, and sustainability patterns while maintaining developer flexibility.
  • SVS209: Containers or serverless functions: A path for cloud-native success – Breakout
    • Explore the fundamental differences between containers and serverless functions through real-world scenarios and insights into choosing the right approach.
  • OPN301: Level up your serverless applications with Powertools for AWS Lambda – Workshop
    • Learn why Powertools for AWS Lambda can be the developer toolkit of choice for serverless workloads.
  • DEV341: From single to multi-tenant: Scaling a mission-critical serverless app
    • Explore how to transition a mission-critical application from a single-tenant to a multi-tenant architecture
  • DEV337: Zero to production serverless in 8 weeks
    • Hear about a real-world project journey, from concept to production in only eight weeks. Expect practical insights, mistakes, tips, and how using the right technologies and development process can deliver results fast.

Building event-driven applications

  • API204: Building event-driven architectures – Workshop
    • Learn about the basics of event-driven design using examples involving Amazon SNS, Amazon SQS, AWS Lambda, Amazon EventBridge, and more.
  • API206: How event-driven architectures can go wrong and how to fix them – Chalk Talk
    • Explore common event-driven pitfalls including YOLO events, god events, observability soup, event loops, and surprise bills.
  • DEV321: Choosing the right serverless compute services
    • Learn when to use AWS serverless compute services like AWS Lambda and Amazon ECS on AWS Fargate and how to integrate them into your application architectures.
  • API307: Event-driven architectures at scale: Manage millions of events – Breakout
    • Discover proven patterns for building high-scale event-driven systems that can be effectively managed across a distributed organization with Amazon EventBridge.
  • SVS206: Building an event sourcing system using AWS serverless technologies – Chalk Talk
    • Explore strategies for building effective event sourcing architectures using AWS serverless technologies to store application state as an append-only event log.
  • COP408: Coding for serverless observability
    • Join this code talk to learn best practices for collecting signals from your serverless applications. Dive deep into techniques to effectively instrument your applications to provide you with optimal observability.

Incorporating orchestration

  • API201: The AWS Step Functions workshop – Workshop
    • Learn about the features of AWS Step Functions through hands-on interactive modules.
  • API203: Building common orchestrated workflows with AWS Step Functions – Builders Session
    • Build three orchestrated workflows, including streamlined data processing with Distributed Map state, external system integration using callback, and implementing the saga pattern.
  • API207: Optimize data processing with built-in AWS Step Functions features – Chalk Talk
    • Learn to optimize your serverless data processing workflows at scale using AWS Step Functions features, including intrinsic functions and Distributed Map state.
  • API402: Building advanced workflows with AWS Step Functions – Breakout
    • Learn how you can use generative AI to generate state machines automatically from textual descriptions and chat with your workflow to optimize it.

Understanding integration patterns

  • API208: Building an integration strategy for the future – Breakout
    • Boost productivity and create better customer experiences by building a modern integration strategy using AWS application, data, and file integration services.
  • API306: Integration patterns for distributed systems – Breakout
    • Learn about common design trade-offs for distributed systems and how to navigate them with design patterns, illustrated with real-world examples.
  • API311: Application integration for platform builders – Breakout
    • Explore the implementation of application integration using serverless components in enterprise environments.

Building APIs and frontends

  • SVS203: Create your first API from scratch with OpenAPI and Amazon API Gateway – Builders Session
    • Learn how to design and provision complete APIs using infrastructure as code following the OpenAPI specification.
  • API303: Building modern API architectures: Which front door should I use? – Chalk Talk
    • Explore options for building modern APIs including REST, GraphQL, and real-time APIs along with their benefits and drawbacks.
  • API304: Building rate-limited solutions on AWS – Chalk Talk
    • Learn some of the best ways to build rate limiting into your systems for improved reliability.
  • API305: Asynchronous frontends: Building seamless event-driven experiences – Breakout
    • Explore patterns to enable asynchronous, event-driven integrations with the frontend designed for architects and frontend, backend, and full-stack engineers.

Diving deep into advanced topics

  • SVS401: Best practices for serverless developers – Breakout
    • Discover architectural best practices, optimizations, and useful shortcuts for building production-ready serverless workloads.
  • SVS403: From serverful to serverless Java – Workshop
    • Learn how to bring your traditional Java Spring application to AWS Lambda with minimal effort and iteratively apply optimizations.
  • SVS406: Scale streaming workloads with AWS Lambda – Chalk Talk
    • Learn how to implement parallel processing techniques for ordered and unordered use cases to address throughput limitations in streaming data processing.

Processing data

  • SVS404: Building serverless distributed data processing workloads – Workshop
    • Learn how serverless technologies like AWS Step Functions and AWS Lambda can help you simplify management and scaling of distributed data processing.
  • API401: Multi-tenant Amazon SQS queues: Mitigating noisy neighbors – Chalk Talk
    • Explore advanced strategies for managing multi-tenant Amazon SQS queues and effective mitigation techniques, including shuffle sharding and overflow queues.
  • SVS321: AWS Lambda and Apache Kafka for real-time data processing applications – Breakout
    • Gain practical insights into building scalable, serverless data processing applications by integrating AWS Lambda with Apache Kafka.

Incorporating generative AI

  • API209: Generative AI at scale: Serverless workflows for enterprise-ready apps – Workshop
    • Learn to build enterprise-ready, scalable generative AI applications that can scale from serving 100 to 100,000 users.
  • API310: Build a meeting summarization solution with generative AI & serverless – Code Talk
    • See live coding of a serverless application for producing meeting summaries with generative AI using Amazon Transcribe and Amazon Bedrock, orchestrated with AWS Step Functions.
  • SVS319: Unlock the power of generative AI with AWS Serverless – Breakout
    • Learn to harness AWS Serverless to build robust, cost-effective generative AI applications. Explore using AWS Step Functions to orchestrate complex AI workflows.
  • SVS325: Secure access to enterprise generative AI with serverless AI gateway – Chalk Talk
    • Explore how to architect a serverless AI gateway on AWS to securely integrate and consume large language models from multiple providers.

Additional resources

For social activities see the Unofficial list of AWS re:Invent Conference and Vendor Parties.

If you are attending re:Invent, connect at our AWS Modern Apps and Open Source Zone in the AWS Expo Village. The AWS Expo Village also includes Serverless and Serverless Containers booths.

If you can not join us in-person, breakout sessions will be available via our YouTube channel after the event.

We look forward to seeing you at re:Invent 2024! For more serverless learning resources, visit Serverless Land.