Tag Archives: Advanced (300)

Implement data quality checks on Amazon Redshift data assets and integrate with Amazon DataZone

Post Syndicated from Lakshmi Nair original https://aws.amazon.com/blogs/big-data/implement-data-quality-checks-on-amazon-redshift-data-assets-and-integrate-with-amazon-datazone/

Data quality is crucial in data pipelines because it directly impacts the validity of the business insights derived from the data. Today, many organizations use AWS Glue Data Quality to define and enforce data quality rules on their data at rest and in transit. However, one of the most pressing challenges faced by organizations is providing users with visibility into the health and reliability of their data assets. This is particularly crucial in the context of business data catalogs using Amazon DataZone, where users rely on the trustworthiness of the data for informed decision-making. As the data gets updated and refreshed, there is a risk of quality degradation due to upstream processes.

Amazon DataZone is a data management service designed to streamline data discovery, data cataloging, data sharing, and governance. It allows your organization to have a single secure data hub where everyone in the organization can find, access, and collaborate on data across AWS, on premises, and even third-party sources. It simplifies the data access for analysts, engineers, and business users, allowing them to discover, use, and share data seamlessly. Data producers (data owners) can add context and control access through predefined approvals, providing secure and governed data sharing. The following diagram illustrates the Amazon DataZone high-level architecture. To learn more about the core components of Amazon DataZone, refer to Amazon DataZone terminology and concepts.

DataZone High Level Architecture

To address the issue of data quality, Amazon DataZone now integrates directly with AWS Glue Data Quality, allowing you to visualize data quality scores for AWS Glue Data Catalog assets directly within the Amazon DataZone web portal. You can access the insights about data quality scores on various key performance indicators (KPIs) such as data completeness, uniqueness, and accuracy.

By providing a comprehensive view of the data quality validation rules applied on the data asset, you can make informed decisions about the suitability of the specific data assets for their intended use. Amazon DataZone also integrates historical trends of the data quality runs of the asset, giving full visibility and indicating if the quality of the asset improved or degraded over time. With the Amazon DataZone APIs, data owners can integrate data quality rules from third-party systems into a specific data asset. The following screenshot shows an example of data quality insights embedded in the Amazon DataZone business catalog. To learn more, see Amazon DataZone now integrates with AWS Glue Data Quality and external data quality solutions.

In this post, we show how to capture the data quality metrics for data assets produced in Amazon Redshift.

Amazon Redshift is a fast, scalable, and fully managed cloud data warehouse that allows you to process and run your complex SQL analytics workloads on structured and semi-structured data. Amazon DataZone natively supports data sharing for Amazon Redshift data assets.

With Amazon DataZone, the data owner can directly import the technical metadata of a Redshift database table and views to the Amazon DataZone project’s inventory. As these data assets gets imported into Amazon DataZone, it bypasses the AWS Glue Data Catalog, creating a gap in data quality integration. This post proposes a solution to enrich the Amazon Redshift data asset with data quality scores and KPI metrics.

Solution overview

The proposed solution uses AWS Glue Studio to create a visual extract, transform, and load (ETL) pipeline for data quality validation and a custom visual transform to post the data quality results to Amazon DataZone. The following screenshot illustrates this pipeline.

Glue ETL pipeline

The pipeline starts by establishing a connection directly to Amazon Redshift and then applies necessary data quality rules defined in AWS Glue based on the organization’s business needs. After applying the rules, the pipeline validates the data against those rules. The outcome of the rules is then pushed to Amazon DataZone using a custom visual transform that implements Amazon DataZone APIs.

The custom visual transform in the data pipeline makes the complex logic of Python code reusable so that data engineers can encapsulate this module in their own data pipelines to post the data quality results. The transform can be used independently of the source data being analyzed.

Each business unit can use this solution by retaining complete autonomy in defining and applying their own data quality rules tailored to their specific domain. These rules maintain the accuracy and integrity of their data. The prebuilt custom transform acts as a central component for each of these business units, where they can reuse this module in their domain-specific pipelines, thereby simplifying the integration. To post the domain-specific data quality results using a custom visual transform, each business unit can simply reuse the code libraries and configure parameters such as Amazon DataZone domain, role to assume, and name of the table and schema in Amazon DataZone where the data quality results need to be posted.

In the following sections, we walk through the steps to post the AWS Glue Data Quality score and results for your Redshift table to Amazon DataZone.

Prerequisites

To follow along, you should have the following:

The solution uses a custom visual transform to post the data quality scores from AWS Glue Studio. For more information, refer to Create your own reusable visual transforms for AWS Glue Studio.

A custom visual transform lets you define, reuse, and share business-specific ETL logic with your teams. Each business unit can apply their own data quality checks relevant to their domain and reuse the custom visual transform to push the data quality result to Amazon DataZone and integrate the data quality metrics with their data assets. This eliminates the risk of inconsistencies that might arise when writing similar logic in different code bases and helps achieve a faster development cycle and improved efficiency.

For the custom transform to work, you need to upload two files to an Amazon Simple Storage Service (Amazon S3) bucket in the same AWS account where you intend to run AWS Glue. Download the following files:

Copy these downloaded files to your AWS Glue assets S3 bucket in the folder transforms (s3://aws-glue-assets–<account id>-<region>/transforms). By default, AWS Glue Studio will read all JSON files from the transforms folder in the same S3 bucket.

customtransform files

In the following sections, we walk you through the steps of building an ETL pipeline for data quality validation using AWS Glue Studio.

Create a new AWS Glue visual ETL job

You can use AWS Glue for Spark to read from and write to tables in Redshift databases. AWS Glue provides built-in support for Amazon Redshift. On the AWS Glue console, choose Author and edit ETL jobs to create a new visual ETL job.

Establish an Amazon Redshift connection

In the job pane, choose Amazon Redshift as the source. For Redshift connection, choose the connection created as prerequisite, then specify the relevant schema and table on which the data quality checks need to be applied.

dqrulesonredshift

Apply data quality rules and validation checks on the source

The next step is to add the Evaluate Data Quality node to your visual job editor. This node allows you to define and apply domain-specific data quality rules relevant to your data. After the rules are defined, you can choose to output the data quality results. The outcomes of these rules can be stored in an Amazon S3 location. You can additionally choose to publish the data quality results to Amazon CloudWatch and set alert notifications based on the thresholds.

Preview data quality results

Choosing the data quality results automatically adds the new node ruleOutcomes. The preview of the data quality results from the ruleOutcomes node is illustrated in the following screenshot. The node outputs the data quality results, including the outcomes of each rule and its failure reason.

previewdqresults

Post the data quality results to Amazon DataZone

The output of the ruleOutcomes node is then passed to the custom visual transform. After both files are uploaded, the AWS Glue Studio visual editor automatically lists the transform as mentioned in post_dq_results_to_datazone.json (in this case, Datazone DQ Result Sink) among the other transforms. Additionally, AWS Glue Studio will parse the JSON definition file to display the transform metadata such as name, description, and list of parameters. In this case, it lists parameters such as the role to assume, domain ID of the Amazon DataZone domain, and table and schema name of the data asset.

Fill in the parameters:

  • Role to assume is optional and can be left empty; it’s only needed when your AWS Glue job runs in an associated account
  • For Domain ID, the ID for your Amazon DataZone domain can be found in the Amazon DataZone portal by choosing the user profile name

datazone page

  • Table name and Schema name are the same ones you used when creating the Redshift source transform
  • Data quality ruleset name is the name you want to give to the ruleset in Amazon DataZone; you could have multiple rulesets for the same table
  • Max results is the maximum number of Amazon DataZone assets you want the script to return in case multiple matches are available for the same table and schema name

Edit the job details and in the job parameters, add the following key-value pair to import the right version of Boto3 containing the latest Amazon DataZone APIs:

--additional-python-modules

boto3>=1.34.105

Finally, save and run the job.

dqrules post datazone

The implementation logic of inserting the data quality values in Amazon DataZone is mentioned in the post Amazon DataZone now integrates with AWS Glue Data Quality and external data quality solutions . In the post_dq_results_to_datazone.py script, we only adapted the code to extract the metadata from the AWS Glue Evaluate Data Quality transform results, and added methods to find the right DataZone asset based on the table information. You can review the code in the script if you are curious.

After the AWS Glue ETL job run is complete, you can navigate to the Amazon DataZone console and confirm that the data quality information is now displayed on the relevant asset page.

Conclusion

In this post, we demonstrated how you can use the power of AWS Glue Data Quality and Amazon DataZone to implement comprehensive data quality monitoring on your Amazon Redshift data assets. By integrating these two services, you can provide data consumers with valuable insights into the quality and reliability of the data, fostering trust and enabling self-service data discovery and more informed decision-making across your organization.

If you’re looking to enhance the data quality of your Amazon Redshift environment and improve data-driven decision-making, we encourage you to explore the integration of AWS Glue Data Quality and Amazon DataZone, and the new preview for OpenLineage-compatible data lineage visualization in Amazon DataZone. For more information and detailed implementation guidance, refer to the following resources:


About the Authors

Fabrizio Napolitano is a Principal Specialist Solutions Architect for DB and Analytics. He has worked in the analytics space for the last 20 years, and has recently and quite by surprise become a Hockey Dad after moving to Canada.

Lakshmi Nair is a Senior Analytics Specialist Solutions Architect at AWS. She specializes in designing advanced analytics systems across industries. She focuses on crafting cloud-based data platforms, enabling real-time streaming, big data processing, and robust data governance.

Varsha Velagapudi is a Senior Technical Product Manager with Amazon DataZone at AWS. She focuses on improving data discovery and curation required for data analytics. She is passionate about simplifying customers’ AI/ML and analytics journey to help them succeed in their day-to-day tasks. Outside of work, she enjoys nature and outdoor activities, reading, and traveling.

How to centrally manage secrets with AWS Secrets Manager

Post Syndicated from Shagun Beniwal original https://aws.amazon.com/blogs/security/how-to-centrally-manage-secrets-with-aws-secrets-manager/

In today’s digital landscape, managing secrets, such as passwords, API keys, tokens, and other credentials, has become a critical task for organizations. For some Amazon Web Services (AWS) customers, centralized management of secrets can be a robust and efficient solution to address this challenge. In this post, we delve into using AWS data protection services such as AWS Secrets Manager and AWS Key Management Service (AWS KMS) to help make secrets management easier in your environment by centrally managing them from a designated AWS account.

Centralized secrets management involves the consolidation of sensitive information into a single, secure repository. This repository acts as a centralized vault where secrets are stored, accessed, and managed with strict security controls. Centralizing secrets can help organizations enforce uniform security policies, streamline access control, and mitigate the risk of unauthorized access or leakage.

This approach offers several key benefits. First, it can enhance security by reducing the threat surface and providing a single point of control for managing access to sensitive information. Additionally, centralized secrets management can facilitate compliance with regulatory requirements by enforcing strict access controls and audit trails.

Furthermore, centralization promotes efficiency and scalability by enabling automated workflows for secret rotation, provisioning, and revocation. This automation reduces administrative tasks and minimizes the risk of human error, enhancing overall operational excellence.

Overview

In this post, we’ll walk you through how to set up a centralized account for managing your secrets and their lifecycle by using AWS Lambda rotation functions. Furthermore, to facilitate efficient access and management across multiple member accounts, we’ll discuss how to establish tunnelling through VPC peering to enable seamless communication between the Centralized Security Account in this architecture and the associated member accounts.

Notably, applications within the member accounts will directly access the secrets stored in the Centralized Security Account through the use of resource policies, streamlining the retrieval process. Additionally, using AWS provided DNS within the Centralized Security Account’s virtual private cloud (VPC) will automate the resolution of database host addresses to their respective control plane IP addresses. This functionality allows AWS Lambda function traffic to efficiently traverse the peering connection, enhancing overall system performance and reliability.

Figure 1 shows the solution architecture. The architecture has four accounts that are managed through AWS Organizations. Out of these four accounts, there are three workload accounts designated as Account A, Account B, and Account C that host the application and database for serving user requests, and a Centralized Security Account from which the secrets will be maintained and managed. VPC 1 from every workload account (Account A, Account B, and Account C) is peered with VPC 1 (part of the Centralized Security Account) to allow communication between workload accounts and the secrets management account. For high availability, secrets are also replicated to a different AWS Region.

Figure 1: Sample solution architecture for centrally managing secrets

Figure 1: Sample solution architecture for centrally managing secrets

Deploy the solution

Follow the steps in this section to deploy the solution.

Step 1: Create secrets, including database secrets, in your Centralized Security Account

First, create the secrets you want to use for this walkthrough. For example, the database secrets will have a following parameters:

{
    "engine": " sql”,
    "username": " admin ",
    "password": "EXAMPLE-PASSWORD",
    "host": "<cross account DB host URL>",
    "dbInstanceIdentifier": "<cross account DB instance identifier>"
    "port": "3306"
}

To create a database secret (console)

  1. Open the AWS Secrets Manager console in the Centralized Security Account.
  2. Choose Store a new secret.
  3. Choose Credentials for other database and provide the user name and password.

    Figure 2: Create and store a new secret using Secrets Manager

    Figure 2: Create and store a new secret using Secrets Manager

  4. For Encryption key, use the instructions in the AWS KMS documentation to create and choose the AWS KMS key that you want Secrets Manager to use to encrypt the secret value. Because you need to access the secret from another AWS account, make sure you are using an AWS KMS customer managed key (CMK).

    Important: Make sure that you do NOT use aws/secretsmanager, because it is an AWS managed key for Secrets Manager and you cannot modify the key policy.

    Figure 3: Select the encryption key to encrypt the secret created

    Figure 3: Select the encryption key to encrypt the secret created

    AWS Secrets Manager makes it possible for you to replicate secrets across multiple AWS Regions to provide regional access and low-latency requirements. If you turn on rotation for your primary secret, Secrets Manager rotates the secret in the primary Region, and the new secret value propagates to the associated Regions. Rotation of replicated secrets does not have to be individually managed.

    Note: When replicating a secret in Secrets Manager, you have the option to choose between using a multi-Region key (MRK) or an independent KMS key in the Region where the secrets are replicated. Your choice depends on your specific requirements such as operational preferences, regulatory compliance, and ease of management.

  5. For Database, select the database from the list of supported database types displayed and provide the host URL in the server address field, the database name, and the port number. Choose Next.

    Figure 4: Selecting the database and providing the database details

    Figure 4: Selecting the database and providing the database details

  6. For Configure secret, provide a secret name (for example, PostgresAppUser) and optionally add a description and tags. The resource permissions required to access the secret from across accounts will be explained later in this post.

    (Optional) Under Replicate secret, select other Regions and customer managed KMS keys from respective Regions to replicate this secret for high availability purposes, and then choose Next.

  7. The next screen will ask you to configure automatic rotation, but you can skip this step for now because you will create the rotation Lambda function in Step 2. Choose Next and then Store to finish saving the secret.

    Note: Secrets Manager rotation uses a Lambda function to update the secret and the database or service. After the secret is created, you must create a rotation Lambda function separately and attach it to the secret for rotating it. This detailed process is covered in the following steps.

Step 2: Deploy the rotation Lambda function where needed

For secrets that require automatic rotation to be turned on, deploy the rotation Lambda function from the serverless application list.

To deploy the rotation Lambda function

  1. In the Centralized Security Account, open the AWS Lambda console.
  2. In the left navigation menu, choose Applications, and then choose Create application.
  3. Choose Serverless Application and then choose the Public Applications tab.
  4. Make sure you have selected the checkbox for Show apps that create custom IAM roles or resource policies.

    Figure 5: Create a rotation Lambda function in the centralized security account for secret rotation

    Figure 5: Create a rotation Lambda function in the centralized security account for secret rotation

  5. In the search field under Serverless application, search for SecretsManager, and the available functions for rotation will be displayed. Choose the Lambda function based on your DB engine type. For example, if the DB engine type is Postgres SQL, select SecretsManagerRDSPostgreSQLRotationSingleUser from the list by choosing the application name.

    Figure 6: Choosing the AWS provided PostgreSQL rotation function (optionally you may choose a different rotation Lambda function)

    Figure 6: Choosing the AWS provided PostgreSQL rotation function (optionally you may choose a different rotation Lambda function)

  6. On the next page, under Application settings, provide the requested details for the following settings:
    1. functionName (for example, PostgresDBUserRotationLambda)
    2. endpoint – For the SecretsManagerRDSPostgreSQLRotationSingleUser option, in the endpoint field, add https://secretsmanager.us-east-1.amazonaws.com. (Choose the Secrets Manager service endpoint based on the Region where the rotation Lambda is created.)
    3. kmsKeyArn – Used by the secret for encryption.
    4. vpcSecurityGroupIds Provide the security group ID for the rotation Lambda function. Under the outbound rules tab of the security group attached to the rotation Lambda, add the required rules for the Lambda function to communicate with the Secrets Manager service endpoint and database. Also, make sure that the security groups attached to your database or service allow inbound connections from the Lambda rotation function.
    5. vpcSubnetIds – When you provide vpcSubnetIDs, provide subnets of a VPC from the Centralized Security Account where you are planning to deploy your rotation Lambda functions.

    Figure 7: Set up rotation Lambda configuration

    Figure 7: Set up rotation Lambda configuration

  7. Select the checkbox next to I acknowledge that this app creates custom IAM roles and resource policies, and then choose Deploy. This will create the required Lambda function to rotate your secret.
  8. Navigate to the Secrets Manager console and edit the secret to turn on automatic rotation (for instructions, see the Secrets Manager documentation).

    Figure 8: Editing the rotation in the Secrets Manager console

    Figure 8: Editing the rotation in the Secrets Manager console

    Set a rotation schedule according to your organization’s data security strategy.

  9. For Lambda rotation function, select the new Lambda function PostgresDbUserRotationLambda that you created in the previous step to associate it with the secret.

    Figure 9: The rotation configuration settings in the Secrets Manager console

    Figure 9: The rotation configuration settings in the Secrets Manager console

Step 3: Set up networking for Lambda to reach the Secrets Manager service endpoint

To provide connectivity to the Lambda function, you can either deploy a VPC endpoint with Private DNS enabled or a NAT gateway.

Deploy a VPC endpoint with Private DNS enabled

To create an Amazon VPC endpoint for AWS Secrets Manager (recommended)

  1. Open the Amazon VPC console, choose Endpoints, and then choose Create endpoint.
  2. For Service category, select AWS services. In the Service Name list, select the Secrets Manager endpoint service named com.amazonaws.<Region>.secretsmanager.

    Figure 10: Create a VPC endpoint for Secrets Manager

    Figure 10: Create a VPC endpoint for Secrets Manager

  3. For VPC, specify the VPC you want to create the endpoint in. This should be the VPC that you selected for hosting centralized secret rotation using the AWS Lambda function.
  4. To create a VPC endpoint, you need to specify the private IP address range in which the endpoint will be accessible. To do this, select the subnet for each Availability Zone (AZ). This restricts the VPC endpoint to the private IP address range specific to each AZ and also creates an AZ-specific VPC endpoint. Specifying more than one subnet-AZ combination helps improve fault tolerance and make the endpoint accessible from a different AZ in case of an AZ failure.
  5. Select the Enable DNS name checkbox for the VPC endpoint. Private DNS resolves the standard Secrets Manager DNS hostname https://secretsmanager.<Region>.amazonaws.com. to the private IP addresses associated with the VPC endpoint specific DNS hostname.

    Figure 11: Set up VPC endpoint configurations

    Figure 11: Set up VPC endpoint configurations

  6. Associate a security group with this endpoint (for instructions, see the AWS PrivateLink documentation). The security group enables you to control the traffic to the endpoint from resources in your VPC. The attached security group should accept inbound connections from the Lambda function for rotation on port 443.

    Figure 12: Attaching the security group to the VPC endpoint

    Figure 12: Attaching the security group to the VPC endpoint

Create a NAT gateway

Alternatively, you can give your function internet access. Place the function in private subnets and route the outbound traffic to a NAT gateway in a public subnet. The NAT gateway has a public IP address and connects to the internet through the VPC’s internet gateway. To create a NAT gateway, follow the steps described in this AWS re:post article.

Step 4: Deploy VPC peering

Next, deploy VPC peering between the Centralized Security Account and the member accounts that hold the database.

To deploy VPC peering

  1. Open the Amazon VPC console in the Centralized Security Account.
  2. In the left navigation pane, choose Peering connections, and then choose Create peering connection.
  3. Configure the following information, and choose Create peering connection when you are done:
    1. Name – You can optionally name your VPC peering connection, for example central_secret_management_vpc_peer.
    2. VPC ID (Requester) – Select the centralized secret management AWS Lambda VPC in your account with which you want to create the VPC peering connection.
    3. Account – Choose Another account.
    4. Account ID – Enter the ID of the AWS account that owns the database.

      Figure 13: Create VPC peering connection

      Figure 13: Create VPC peering connection

    5. VPC ID (Accepter) – Enter the ID of the database VPC with which to create the VPC peering connection.

      Figure 14: Create VPC peering connection – Entering the VPC ID

      Figure 14: Create VPC peering connection – Entering the VPC ID

  4. From the database account, navigate to the Amazon VPC console. Choose Peering connections and then choose Accept request.

    Figure 15: Accepting the VPC peering request from the database account (Accounts A, B, and C)

    Figure 15: Accepting the VPC peering request from the database account (Accounts A, B, and C)

  5. Add a route to the route tables in both VPCs so that you can send and receive traffic across the peering connection. Each table has a local route and a route that sends traffic for the peer VPC to the VPC peering connection.

    Figure 16: Sample table to show VPC peering connections between the Centralized Security Account and application/database accounts

    Figure 16: Sample table to show VPC peering connections between the Centralized Security Account and application/database accounts

  6. Perform the following steps in the Centralized Security Account:
    1. Open the Amazon VPC console in the Centralized Security Account.
    2. Select the Centralized Security Account Lambda VPC. Under Details, choose Main route table.
    3. Choose Edit routes, and then choose Add routes. Under Destination, add the database VPC CIDR (172.31.0.0/16) in an empty field. Under Target, select the peering connection you created in Step 3.
  7. Perform the following steps in Account 2, where the application/database is hosted:
    1. Open the VPC console in the database account.
    2. Select the Centralized Security Account Lambda VPC and then, under Details, choose Main route table.
    3. Choose Edit routes, and then choose Add routes. Under Destination, add the rotation Lambda VPC CIDR (10.0.0.0/16) in an empty field. Under Target, select the peering connection you created in Step 3.

Step 5: Set up resource-based policies on each secret

After the secrets are deployed into the Centralized Security Account, to allow application roles or users in other accounts to access the secrets (known as cross-account access), you must allow access in both a resource policy and in an identity policy. This is different than granting access to identities in the same account rather than the secret.

To set up resource-based policies on each secret

  1. Attach a resource policy to the secret in the Centralized Security Account by using the following steps:
    1. Open the Secrets Manager console. Remember to choose the Region that is appropriate for your setup.
    2. From the list of secrets, choose your secret.
    3. On the Secret details page, choose the Overview tab.
    4. Under Resource permissions, choose Edit permissions.
    5. In the Code field, attach or append the following resource policy statement, and then choose Save:
    {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Effect": "Allow",
          "Principal": {
            "AWS": "arn:aws:iam::<account2-id>:role/ApplicationRole"
          },
          "Action": "secretsmanager:GetSecretValue",
          "Resource": "<ARN of secret to which this policy is attached>"
        }
      ]
    }

  2. Add the following resource policy statement to the key policy for the KMS key in the Centralized Security Account.
    {
          "Effect": "Allow",
          "Principal": {
            "AWS": "arn:aws:iam::<account2-id>:role/ApplicationRole"
          },
          "Action": [
            "kms:Decrypt",
            "kms:DescribeKey"
          ],
          "Resource": "<kms-key-resource-arn>"
        }

    If there exists no policy on the key, add the following policy to the key.

    {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Effect": "Allow",
          "Principal": {
            "AWS": "arn:aws:iam::<account2-id>:role/ApplicationRole"
          },
          "Action": [
            "kms:Decrypt",
            "kms:DescribeKey"
          ],
          "Resource": "<kms-key-resource-arn>"
        }
      ]
    }

  3. Attach an identity policy to the identity in the accounts where you hosted your applications to provide access to the secret and the KMS key used to encrypt the secret.
    {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Effect": "Allow",
          "Action": "secretsmanager:GetSecretValue",
          "Resource": "arn:aws:secretsmanager:<your-region>:<centralized-security-account-id>:secret:<secret-id>"
        },
        {
          "Effect": "Allow",
          "Action": "kms:Decrypt",
          "Resource": "arn:aws:kms:<your-region>:<centralized-security-account-id>:key/<key-id>"
        }
      ]
    }

The access policies mentioned here are just for the example in this post. In a production environment, only provide the needed granular permissions by exercising least privilege principles.

What challenges does this solution present, and how can you overcome them?

Along with the advantages discussed in this post, there are a few challenges you should anticipate while deploying this solution:

  1. Currently there is a maximum of 20,480 characters allowed in a resource-based permissions policy attached to a secret. For organizations where a large number of external accounts need to be given access to a secret, you will need to keep this quota in mind.
  2. There is also a limit on the total number of active VPC peering connections per VPC. By default, the limit is 50 connections, but this is adjustable up to 125. If you require more connections across VPCs, you can use other solutions, like a transit gateway, as an alternative.
  3. As the number of applications that require access to secrets from the Centralized Security Account increases, the number of external accesses will also increase, and access control might become difficult over time. To reduce the number of external accounts that have access to the Centralized Security Account, you may choose to use AWS IAM Access Analyzer.

Conclusion

In this post, we provided you with a step-by-step solution to establish a Centralized Security Account that uses the AWS Secrets Manager service for securely storing your secrets in a central place. The post outlined the process of deploying AWS Lambda functions to facilitate automatic rotation of necessary secrets. Furthermore, we delved into the implementation of VPC peering to provide uninterrupted connectivity between the rotation function and your databases or applications housed in different AWS accounts, helping to ensure smooth rotation.

Finally, we discussed the essential policies that are needed to enable applications to use these secrets through resource-based policies. This implementation provides a way for you to conveniently monitor and audit your secrets.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Shagun Beniwal

Shagun Beniwal
Shagun is a Technical Account Manager at AWS. He manages Global System Integrators (GSIs) and Partners operating on AWS Enterprise Support. He is a member of the internal security community with focus areas in threat detection & incident response, infrastructure security, and IAM. Shagun helps customers achieve strategic business outcomes in security, resilience, cost optimization, and operations. You can follow Shagun on LinkedIn.

Navaneeth Krishnan Venugopal

Navaneeth Krishnan Venugopal
Navaneeth is a Cloud Support – Security Engineer II at AWS and an AWS Secrets Manager subject matter expert (SME). He is passionate about cybersecurity and helps provide tailored, secure solutions for a broad spectrum of technical issues faced by customers. Navaneeth has a focus on security and compliance and enjoys helping customers architect secure solutions on AWS.

Build a serverless data quality pipeline using Deequ on AWS Lambda

Post Syndicated from Vivek Mittal original https://aws.amazon.com/blogs/big-data/build-a-serverless-data-quality-pipeline-using-deequ-on-aws-lambda/

Poor data quality can lead to a variety of problems, including pipeline failures, incorrect reporting, and poor business decisions. For example, if data ingested from one of the systems contains a high number of duplicates, it can result in skewed data in the reporting system. To prevent such issues, data quality checks are integrated into data pipelines, which assess the accuracy and reliability of the data. These checks in the data pipelines send alerts if the data quality standards are not met, enabling data engineers and data stewards to take appropriate actions. Example of these checks include counting records, detecting duplicate data, and checking for null values.

To address these issues, Amazon built an open source framework called Deequ, which performs data quality at scale. In 2023, AWS launched AWS Glue Data Quality, which offers a complete solution to measure and monitor data quality. AWS Glue uses the power of Deequ to run data quality checks, identify records that are bad, provide a data quality score, and detect anomalies using machine learning (ML). However, you may have very small datasets and require faster startup times. In such instances, an effective solution is running Deequ on AWS Lambda.

In this post, we show how to run Deequ on Lambda. Using a sample application as reference, we demonstrate how to build a data pipeline to check and improve the quality of data using AWS Step Functions. The pipeline uses PyDeequ, a Python API for Deequ and a library built on top of Apache Spark to perform data quality checks. We show how to implement data quality checks using the PyDeequ library, deploy an example that showcases how to run PyDeequ in Lambda, and discuss the considerations using Lambda for running PyDeequ.

To help you get started, we’ve set up a GitHub repository with a sample application that you can use to practice running and deploying the application.

Since you are reading this post you may also be interested in the following:

Solution overview

In this use case, the data pipeline checks the quality of Airbnb accommodation data, which includes ratings, reviews, and prices, by neighborhood. Your objective is to perform the data quality check of the input file. If the data quality check passes, then you aggregate the price and reviews by neighborhood. If the data quality check fails, then you fail the pipeline and send a notification to the user. The pipeline is built using Step Functions and comprises three primary steps:

  • Data quality check – This step uses a Lambda function to verify the accuracy and reliability of the data. The Lambda function uses PyDeequ, a library for data quality checks. As PyDeequ runs on Spark, the example employs the Spark Runtime for AWS Lambda (SoAL) framework, which makes it straightforward to run a standalone installation of Spark in Lambda. The Lambda function performs data quality checks and stores the results in an Amazon Simple Storage Service (Amazon S3) bucket.
  • Data aggregation – If the data quality check passes, the pipeline moves to the data aggregation step. This step performs some calculations on the data using a Lambda function that uses Polars, a DataFrames library. The aggregated results are stored in Amazon S3 for further processing.
  • Notification – After the data quality check or data aggregation, the pipeline sends a notification to the user using Amazon Simple Notification Service (Amazon SNS). The notification includes a link to the data quality validation results or the aggregated data.

The following diagram illustrates the solution architecture.

Implement quality checks

The following is an example of data from the sample accommodations CSV file.

id name host_name neighbourhood_group neighbourhood room_type price minimum_nights number_of_reviews
7071 BrightRoom with sunny greenview! Bright Pankow Helmholtzplatz Private room 42 2 197
28268 Cozy Berlin Friedrichshain for1/6 p Elena Friedrichshain-Kreuzberg Frankfurter Allee Sued FK Entire home/apt 90 5 30
42742 Spacious 35m2 in Central Apartment Desiree Friedrichshain-Kreuzberg suedliche Luisenstadt Private room 36 1 25
57792 Bungalow mit Garten in Berlin Zehlendorf Jo Steglitz – Zehlendorf Ostpreu√üendamm Entire home/apt 49 2 3
81081 Beautiful Prenzlauer Berg Apt Bernd+Katja 🙂 Pankow Prenzlauer Berg Nord Entire home/apt 66 3 238
114763 In the heart of Berlin! Julia Tempelhof – Schoeneberg Schoeneberg-Sued Entire home/apt 130 3 53
153015 Central Artist Appartement Prenzlauer Berg Marc Pankow Helmholtzplatz Private room 52 3 127

In a semi-structured data format such as CSV, there is no inherent data validation and integrity checks. You need to verify the data against accuracy, completeness, consistency, uniqueness, timeliness, and validity, which are commonly referred as the six data quality dimensions. For instance, if you want to display the name of the host for a particular property on a dashboard, but the host’s name is missing in the CSV file, this would be an issue of incomplete data. Completeness checks can include looking for missing records, missing attributes, or truncated data, among other things.

As part of the GitHub repository sample application, we provide a PyDeequ script that will perform the quality validation checks on the input file.

The following code is an example of performing the completeness check from the validation script:

checkCompleteness = VerificationSuite(spark)
.onData(dataset) \
.isComplete("host_name")

The following is an example of checking for uniqueness of data:

checkCompleteness = VerificationSuite(spark)
.onData(dataset) \
.isUnique ("id")

You can also chain multiple validation checks as follows:

checkResult = VerificationSuite(spark) \
.onData(dataset) \
.isComplete("name") \
.isUnique("id") \
.isComplete("host_name") \
.isComplete("neighbourhood") \
.isComplete("price") \
.isNonNegative("price")) \
.run()

The following is an example of making sure 99% or more of the records in the file include host_name:

checkCompleteness = VerificationSuite(spark)
.onData(dataset) \
.hasCompleteness("host_name", lambda x: x >= 0.99)

Prerequisites

Before you get started, make sure you complete the following prerequisites:

  1. You should have an AWS account.
  2. Install and configure the AWS Command Line Interface (AWS CLI).
  3. Install the AWS SAM CLI.
  4. Install Docker community edition.
  5. You should have Python 3

Run Deequ on Lambda

To deploy the sample application, complete the following steps:

  1. Clone the GitHub repository.
  2. Use the provided AWS CloudFormation template to create the Amazon Elastic Container Registry (Amazon ECR) image that will be used to run Deequ on Lambda.
  3. Use the AWS SAM CLI to build and deploy the rest of the data pipeline to your AWS account.

For detailed deployment steps, refer to the GitHub repository Readme.md.

When you deploy the sample application, you’ll find that the DataQuality function is in a container packaging format. This is because the SoAL library required for this function is larger than the 250 MB limit for zip archive packaging. During the AWS Serverless Application Model (AWS SAM) deployment process, a Step Functions workflow is also created, along with the necessary data required to run the pipeline.

Run the workflow

After the application has been successfully deployed to your AWS account, complete the following steps to run the workflow:

  1. Go to the S3 bucket that was created earlier.

You will notice a new bucket with the prefix as your stack name.

  1. Follow the instructions in the GitHub repository to upload the Spark script to this S3 bucket. This script is used to perform data quality checks.
  2. Subscribe to the SNS topic created to receive success or failure email notifications as explained in the GitHub repository.
  3. Open the Step Functions console and run the workflow prefixed DataQualityUsingLambdaStateMachine with default inputs.
  4. You can test both success and failure scenarios as explained in the instructions in the GitHub repository.

The following figure illustrates the workflow of the Step Functions state machine.

Review the quality check results and metrics

To review the quality check results, you can navigate to the same S3 bucket. Navigate to the OUTPUT/verification-results folder to see the quality check verification results. Open the file name starting with the prefix part. The following table is a snapshot of the file.

check check_level check_status constraint constraint_status
Accomodations Error Success SizeConstraint(Size(None)) Success
Accomodations Error Success CompletenessConstraint(Completeness(name,None)) Success
Accomodations Error Success UniquenessConstraint(Uniqueness(List(id),None)) Success
Accomodations Error Success CompletenessConstraint(Completeness(host_name,None)) Success
Accomodations Error Success CompletenessConstraint(Completeness(neighbourhood,None)) Success
Accomodations Error Success CompletenessConstraint(Completeness(price,None)) Success

Check_status suggests if the quality check was successful or a failure. The Constraint column suggests the different quality checks that were done by the Deequ engine. Constraint_status suggests the success or failure for each of the constraint.

You can also review the quality check metrics generated by Deequ by navigating to the folder OUTPUT/verification-results-metrics. Open the file name starting with the prefix part. The following table is a snapshot of the file.

entity instance name value
Column price is non-negative Compliance 1
Column neighbourhood Completeness 1
Column price Completeness 1
Column id Uniqueness 1
Column host_name Completeness 0.998831356
Column name Completeness 0.997348076

For the columns with a value of 1, all the records of the input file satisfy the specific constraint. For the columns with a value of 0.99, 99% of the records satisfy the specific constraint.

Considerations for running PyDeequ in Lambda

Consider the following when deploying this solution:

  • Running SoAL on Lambda is a single-node deployment, but is not limited to a single core; a node can have multiple cores in Lambda, which allows for distributed data processing. Adding more memory in Lambda proportionally increases the amount of CPU, increasing the overall computational power available. Multiple CPU with single-node deployment and the quick startup time of Lambda results in faster job processing when it comes to Spark jobs. Additionally, the consolidation of cores within a single node enables faster shuffle operations, enhanced communication between cores, and improved I/O performance.
  • For Spark jobs that run longer than 15 minutes or larger files (more than 1 GB) or complex joins that require more memory and compute resource, we recommend AWS Glue Data Quality. SoAL can also be deployed in Amazon ECS.
  • Choosing the right memory setting for Lambda functions can help balance the speed and cost. You can automate the process of selecting different memory allocations and measuring the time taken using Lambda power tuning.
  • Workloads using multi-threading and multi-processing can benefit from Lambda functions powered by an AWS Graviton processor, which offers better price-performance. You can use Lambda power tuning to run with both x86 and ARM architecture and compare results to choose the optimal architecture for your workload.

Clean up

Complete the following steps to clean up the solution resources:

  1. On the Amazon S3 console, empty the contents of your S3 bucket.

Because this S3 bucket was created as part of the AWS SAM deployment, the next step will delete the S3 bucket.

  1. To delete the sample application that you created, use the AWS CLI. Assuming you used your project name for the stack name, you can run the following code:
sam delete --stack-name "<your stack name>"
  1. To delete the ECR image you created using CloudFormation, delete the stack from the AWS CloudFormation console.

For detailed instructions, refer to the GitHub repository Readme.md file.

Conclusion

Data is crucial for modern enterprises, influencing decision-making, demand forecasting, delivery scheduling, and overall business processes. Poor quality data can negatively impact business decisions and efficiency of the organization.

In this post, we demonstrated how to implement data quality checks and incorporate them in the data pipeline. In the process, we discussed how to use the PyDeequ library, how to deploy it in Lambda, and considerations when running it in Lambda.

You can refer to Data quality prescriptive guidance for learning about best practices for implementing data quality checks. Please refer to Spark on AWS Lambda blog to learn about running analytics workloads using AWS Lambda.


About the Authors

Vivek Mittal is a Solution Architect at Amazon Web Services. He is passionate about serverless and machine learning technologies. Vivek takes great joy in assisting customers with building innovative solutions on the AWS cloud platform.

John Cherian is Senior Solutions Architect at Amazon Web Services helps customers with strategy and architecture for building solutions on AWS.

Uma Ramadoss is a Principal Solutions Architect at Amazon Web Services, focused on the Serverless and Integration Services. She is responsible for helping customers design and operate event-driven cloud-native applications using services like Lambda, API Gateway, EventBridge, Step Functions, and SQS. Uma has a hands on experience leading enterprise-scale serverless delivery projects and possesses strong working knowledge of event-driven, micro service and cloud architecture.

Improve the resilience of Amazon Managed Service for Apache Flink application with system-rollback feature

Post Syndicated from Subham Rakshit original https://aws.amazon.com/blogs/big-data/improve-the-resilience-of-amazon-managed-service-for-apache-flink-application-with-system-rollback-feature/

“Everything fails all the time” – Werner Vogels, CTO Amazon

Although customers always take precautionary measures when they build applications, application code and configuration errors can still happen, causing application downtime. To mitigate this, Amazon Managed Service for Apache Flink has built a new layer of resilience by allowing customers to opt for the system-rollback feature that will seamlessly revert the application to a previous running version, thereby improving application stability and high availability.

Apache Flink is an open source distributed processing engine that offers powerful programming interfaces for stream and batch processing. It also offers first-class support for stateful processing and event time semantics. Apache Flink supports multiple programming languages, including Java, Python, Scala, SQL, and multiple APIs with different levels of abstraction. These APIs can be used interchangeably in the same application.

Managed Service for Apache Flink is a fully managed, serverless experience in running Apache Flink applications, and it now supports Apache Flink 1.19.1, the latest released version of Apache Flink at the time of this writing.

This post explores how to use the system-rollback feature in Managed Service for Apache Flink.We discuss how this functionality improves your application’s resilience by providing a highly available Flink application. Through an example, you will also learn how to use the APIs to have more visibility of the application’s operations. This would help in troubleshooting application and configuration issues.

Error scenarios for system-rollback

Managed Service for Apache Flink operates under a shared responsibility model. This means the service owns the infrastructure to run Flink applications that are secure, durable, and highly available. Customers are responsible for making sure application code and configurations are correct. There have been cases where updating the Flink application failed due to code bugs, incorrect configuration, or insufficient permissions. Here are a few examples of common error scenarios:

  1. Code bugs, including any runtime errors encountered. For example, null values are not appropriately handled in the code, resulting in NullPointerException
  2. The Flink application is updated with parallelism higher than the max parallelism configured for the application.
  3. The application is updated to run with incorrect subnets for a virtual private cloud (VPC) application which results in failure at Flink job startup.

As of this writing, the Managed Service for Apache Flink application still shows a RUNNING status when such errors occur, despite the fact that the underlying Flink application cannot process the incoming events and recover from the errors.

Errors can also happen during application auto scaling. For example, when the application scales up but runs into issues restoring from a savepoint due to operator mismatch between the snapshot and the Flink job graph. This can happen if you failed to set the operator ID using the uid method or changed it in a new application.

You may also receive a snapshot compatibility error when upgrading to a new Apache Flink version. Although stateful version upgrades of Apache Flink runtime are generally compatible with very few exceptions, you can refer to the Apache Flink state compatibility table and Managed Service for Apache Flink documentation for more details.

In such scenarios, you can either perform a force-stop operation, which stops the application without taking a snapshot, or you can roll back the application to the previous version using the RollbackApplication API. Both processes need customer intervention to recover from the issue.

Automatic rollback to the previous application version

With the system-rollback feature, Managed Service for Apache Flink will perform an automatic RollbackApplication operation to restore the application to the previous version when an update operation or a scaling operation fails and you encounter the error scenarios discussed previously.

If the rollback is successful, the Flink application is restored to the previous application version with the latest snapshot. The Flink application is put into a RUNNING state and continues processing events. This process results in high availability of the Flink application with improved resilience under minimal downtime. If the system-rollback fails, the Flink application will be in a READY state. If this is the case, you need to fix the error and restart the application.

However, if a Managed Service for Apache Flink application is started with application or configuration issues, the service will not start the application. Instead, it will return in the READY state. This is a default behavior regardless of whether system-rollback is enabled or not.

System-rollback is performed before the application transitions to RUNNING status. Automatic rollback will not be performed if a Managed Service for Apache Flink application has already successfully transitioned to RUNNING status and later faces runtime issues such as checkpoint failures or job failures. However, customers can trigger the RollbackApplication API themselves if they want to roll back on runtime errors.

Here is the state transition flowchart of system-rollback.

Amazon Managed Service for Apache Flink State Transition

System-rollback is an opt-in feature that needs you to enable it using the console or the API. To enable it using the API, invoke the UpdateApplication API with the following configuration. This feature is available to all Apache Flink versions supported by Managed Service for Apache Flink.

Each Managed Service for Apache Flink application has a version ID, which tracks the application code and configuration for that specific version. You can get the current application version ID from the AWS console of the Managed Service for Apache Flink application.

aws kinesisanalyticsv2 update-application \
	--application-name sample-app-system-rollback-test \
	--current-application-version-id 5 \
	--application-configuration-update "{\"ApplicationSystemRollbackConfigurationUpdate\": {\"RollbackEnabledUpdate\": true}}" \
	--region us-west-1

Application operations observability

Observability of the application versions change is of utmost importance because Flink applications can be rolled back seamlessly from newly upgraded versions to previous versions in the event of application and configuration errors. First, visibility of the version history will provide chronological information about the operations performed on the application. Second, it will help with debugging because it shows the underlying error and why the application was rolled back. This is so that the issues can be fixed and retried.

For this, you have two additional APIs to invoke from the AWS Command Line Interface (AWS CLI):

  1. ListApplicationOperations – This API will list all the operations, such as UpdateApplication, ApplicationMaintenance, and RollbackApplication, performed on the application in a reverse chronological order.
  2. DescribeApplicationOperation – This API will provide details of a specific operation listed by the ListApplicationOperations API including the failure details.

Although these two new APIs can help you understand the error, you should also refer to the AWS CloudWatch logs for your Flink application for troubleshooting help. In the logs, you can find additional details, including the stack trace. Once you identify the issue, fix it and update the Flink application.

For troubleshooting information, refer to documentation .

System-rollback process flow

The following image shows a Managed Service for Apache Flink application in RUNNING state with Version ID: 3. The application is consuming data successfully from the Amazon Kinesis Data Stream source, processing it, and writing it into another Kinesis Data Stream sink.

Also, from the Apache Flink Dashboard, you can see the Status of the Flink application is RUNNING.

To demonstrate the system-rollback, we updated the application code to intentionally introduce an error. From the application main method, an exception is thrown, as shown in the following code.

throw new Exception("Exception thrown to demonstrate system-rollback");

While updating the application with the latest jar, the Version ID is incremented to 4, and the application Status shows it is UPDATING, as shown in the following screenshot.

After some time, the application rolls back to the previous version, Version ID: 3, as shown in the following screenshot.

The application now has successfully gone back to version 3 and continues to process events, as shown by Status RUNNING in the following screenshot.

To troubleshoot what went wrong in version 4, list all the application versions for the Managed Service for Apache Flink application: sample-app-system-rollback-test.

aws kinesisanalyticsv2 list-application-operations \
    --application-name sample-app-system-rollback-test \
    --region us-west-1

This shows the list of operations done on Flink application: sample-app-system-rollback-test

{
  "ApplicationOperationInfoList": [
    {
      "Operation": "SystemRollbackApplication",
      "OperationId": "Z4mg9iXiXXXX",
      "StartTime": "2024-06-20T16:52:13+01:00",
      "EndTime": "2024-06-20T16:54:49+01:00",
      "OperationStatus": "SUCCESSFUL"
    },
    {
      "Operation": "UpdateApplication",
      "OperationId": "zIxXBZfQXXXX",
      "StartTime": "2024-06-20T16:50:04+01:00",
      "EndTime": "2024-06-20T16:52:13+01:00",
      "OperationStatus": "FAILED"
    },
    {
      "Operation": "StartApplication",
      "OperationId": "BPyrMrrlXXXX",
      "StartTime": "2024-06-20T15:26:03+01:00",
      "EndTime": "2024-06-20T15:28:05+01:00",
      "OperationStatus": "SUCCESSFUL"
    }
  ]
}

Review the details of the UpdateApplication operation and note the OperationId. If you use the AWS CLI and APIs to update the application, then the OperationId can be obtained from the UpdateApplication API response. To investigate what went wrong, you can use OperationId to invoke describe-application-operation.

Use the following command to invoke describe-application-operation.

aws kinesisanalyticsv2 describe-application-operation \
    --application-name sample-app-system-rollback-test \
    --operation-id zIxXBZfQXXXX \
    --region us-west-1

This will show the details of the operation, including the error.

{
    "ApplicationOperationInfoDetails": {
        "Operation": "UpdateApplication",
        "StartTime": "2024-06-20T16:50:04+01:00",
        "EndTime": "2024-06-20T16:52:13+01:00",
        "OperationStatus": "FAILED",
        "ApplicationVersionChangeDetails": {
            "ApplicationVersionUpdatedFrom": 3,
            "ApplicationVersionUpdatedTo": 4
        },
        "OperationFailureDetails": {
            "RollbackOperationId": "Z4mg9iXiXXXX",
            "ErrorInfo": {
                "ErrorString": "org.apache.flink.runtime.rest.handler.RestHandlerException: Could not execute application.\n\tat org.apache.flink.runtime.webmonitor.handlers.JarRunOverrideHandler.lambda$handleRequest$4(JarRunOverrideHandler.java:248)\n\tat java.base/java.util.concurrent.CompletableFuture.uniHandle(CompletableFuture.java:930)\n\tat java.base/java.util.concurrent.CompletableFuture$UniHandle.tryFire(CompletableFuture.java:907)\n\tat java.base/java.util.concurrent.CompletableFuture.postComplete(CompletableFuture.java:506)\n\tat java.ba"
            }
        }
    }
}

Review the CloudWatch logs for the actual error information. The following code shows the same error with the complete stack trace, which demonstrates the underlying problem.

Amazon Managed Service for Apache Flink failed to transition the application to the desired state. The application is being rolled-back to the previous state. Please investigate the following error. org.apache.flink.runtime.rest.handler.RestHandlerException: Could not execute application.
at org.apache.flink.runtime.webmonitor.handlers.JarRunOverrideHandler.lambda$handleRequest$4(JarRunOverrideHandler.java:248)
at java.base/java.util.concurrent.CompletableFuture.uniHandle(CompletableFuture.java:930)
at java.base/java.util.concurrent.CompletableFuture$UniHandle.tryFire(CompletableFuture.java:907)
...
...
...
Caused by: java.lang.Exception: Exception thrown to demonstrate system-rollback
at com.amazonaws.services.msf.StreamingJob.main(StreamingJob.java:101)
at java.base/jdk.internal.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
at java.base/jdk.internal.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
at java.base/jdk.internal.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
at java.base/java.lang.reflect.Method.invoke(Method.java:566)
at org.apache.flink.client.program.PackagedProgram.callMainMethod(PackagedProgram.java:355)
... 12 more

Finally, you need to fix the issue and redeploy the Flink application.

Conclusion

This post has explained how to enable the system-rollback feature and how it helps to minimize application downtime in bad deployment scenarios. Moreover, we have explained how this feature will work, as well as how to troubleshoot underlying problems. We hope you found this post helpful and that it provided insight into how to improve the resilience and availability of your Flink application. We encourage you to enable the feature to improve resilience of your Managed Service for Apache Flink application.

To learn more about system-rollback, refer to the AWS documentation.


About the author

Subham Rakshit is a Senior Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build streaming architectures so they can get value from analyzing their streaming data. His two little daughters keep him occupied most of the time outside work, and he loves solving jigsaw puzzles with them. Connect with him on LinkedIn.

Use AWS Glue to streamline SFTP data processing

Post Syndicated from Seun Akinyosoye original https://aws.amazon.com/blogs/big-data/use-aws-glue-to-streamline-sftp-data-processing/

In today’s data-driven world, seamless integration and transformation of data across diverse sources into actionable insights is paramount. AWS Glue is a serverless data integration service that helps analytics users to discover, prepare, move, and integrate data from multiple sources for analytics, machine learning (ML), and application development. With AWS Glue, you can discover and connect to hundreds of diverse data sources and manage your data in a centralized data catalog. It enables you to visually create, run, and monitor extract, transform, and load (ETL) pipelines to load data into your data lakes.

In this blog post, we explore how to use the SFTP Connector for AWS Glue from the AWS Marketplace to efficiently process data from Secure File Transfer Protocol (SFTP) servers into Amazon Simple Storage Service (Amazon S3), further empowering your data analytics and insights.

Introducing the SFTP connector for AWS Glue

The SFTP connector for AWS Glue simplifies the process of connecting AWS Glue jobs to extract data from SFTP storage and to load data into SFTP storage. This connector provides comprehensive access to SFTP storage, facilitating cloud ETL processes for operational reporting, backup and disaster recovery, data governance, and more.

Solution overview

In this example, you use AWS Glue Studio to connect to an SFTP server, then enrich that data and upload it to Amazon S3. The SFTP connector is used to manage the connection to the SFTP server. You will load the event data from the SFTP site, join it to the venue data stored on Amazon S3, apply transformations, and store the data in Amazon S3. The event and venue files are from the TICKIT dataset.

The TICKIT dataset tracks sales activity for the fictional TICKIT website, where users buy and sell tickets online for sporting events, shows, and concerts. In this dataset, analysts can identify ticket movement over time, success rates for sellers, and best-selling events, venues, and seasons.

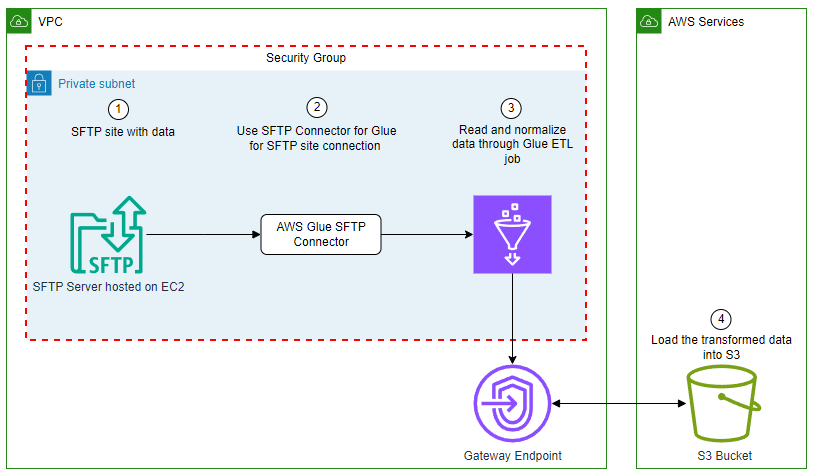
For this example, you use AWS Glue Studio to develop a visual ETL pipeline. This pipeline will read data from an SFTP server, perform transformations, and then load the transformed data into Amazon S3. The following diagram illustrates this architecture.

solution overview

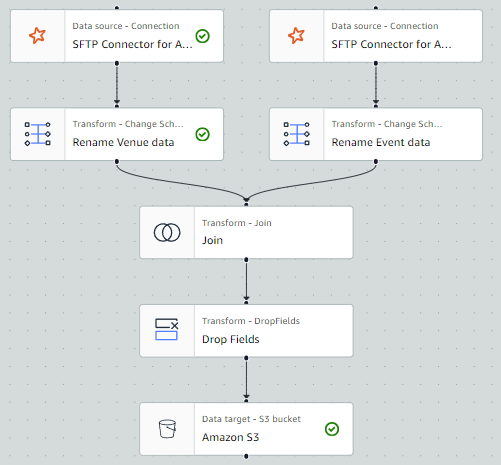
By the end of this post, your visual ETL job will resemble the following screenshot.

final solution

Prerequisites

For this solution, you need the following:

  • Subscribe to the SFTP Connector for AWS Glue in the AWS Marketplace.
  • Access to an SFTP server with permissions to upload and download data.
    • If the SFTP server is hosted on Amazon Elastic Compute Cloud (Amazon EC2), we recommend that the network communication between the SFTP server and the AWS Glue job happens within the virtual private cloud (VPC) as pictured in the preceding architecture diagram. Running your Glue job within a VPC and security group will be discussed further in the steps to create the AWS Glue job.
    • If the SFTP server is hosted within your on-premises network, we recommend that the network communication between the SFTP server and the Glue job happens through VPN or AWS DirectConnect.
  • Access to an S3 bucket or the permissions to create an S3 bucket. We recommend that you connect to that bucket using a gateway endpoint. This will allow you to connect to your S3 bucket directly from your VPC. If you need to create an S3 bucket to store the results, complete the following steps:
    1. On the Amazon S3 console, choose Buckets in the navigation pane.
    2. Choose Create bucket.
    3. For Name, enter a globally unique name for your bucket; for example, tickit-use1-<accountnumber>.
    4. Choose Create bucket.
    5. For this demonstration, create a folder with the name tickit in your S3 bucket.
    6. Create the gateway endpoint.
  • Create an AWS Identity and Access Management (IAM) role for the AWS Glue ETL job. You must specify an IAM role for the job to use. The role must grant access to all resources used by the job, including Amazon S3 (for any sources, targets, scripts, and temporary directories) and AWS Secrets Manager. For instructions, see Configure an IAM role for your ETL job.

Load dataset to SFTP site

Load the allevents_pipe.txt file and venue_pipe.txt file from the TICKIT dataset to your SFTP server.

Store SFTP server sign-in credentials

An AWS Glue connection is a Data Catalog object that stores connection information, such as URI strings and location to credentials that are stored in a Secrets Manager secret.

To store the SFTP server username and password in Secrets Manager, complete the following steps:

  1. On the Secrets Manager console, choose Secrets in the navigation pane.
  2. Choose Store a new secret.
  3. Select Other type of secret.
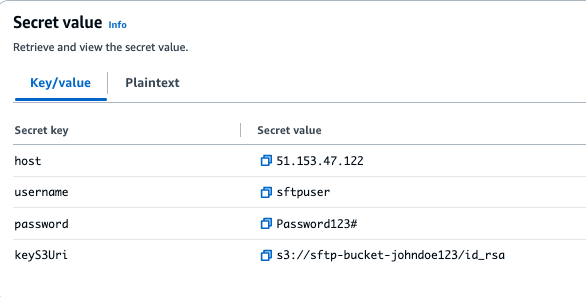
  4. Enter host as Secret key and your SFTP server’s IP address (for example, 153.47.122) as the Secret value, then choose Add row.
  5. Enter the username as Secret key and your SFTP username as Secret value, then choose Add row.
  6. Enter password as Secret key and your SFTP password as Secret value, then choose Add row.
  7. Enter keyS3Uri as Secret Key and the Amazon S3 location of your SFTP secret key file as Secret value

Note: Secret Value is the full S3 path where the SFTP server key file is stored. For example:s3://sftp-bucket-johndoe123/id_rsa.

  1. For Secret name, enter a descriptive name, then choose Next.
  2. Choose Next to move to the review step, then choose Store.

secret value

Create a connection to the SFTP server in AWS Glue

Complete the following steps to create your connection to the SFTP server.

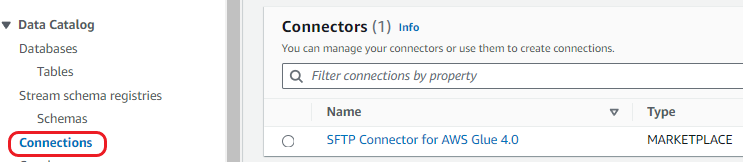
  1. On the AWS Glue console, under Data Catalog in the navigation pane, choose Connections.

creating sftp connection from marketplace

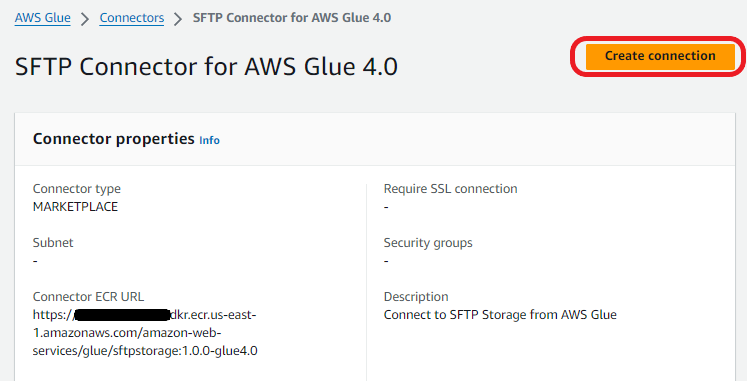
  1. Select the SFTP connector for AWS Glue 4.0. Then choose Create connection.

using sftp connector

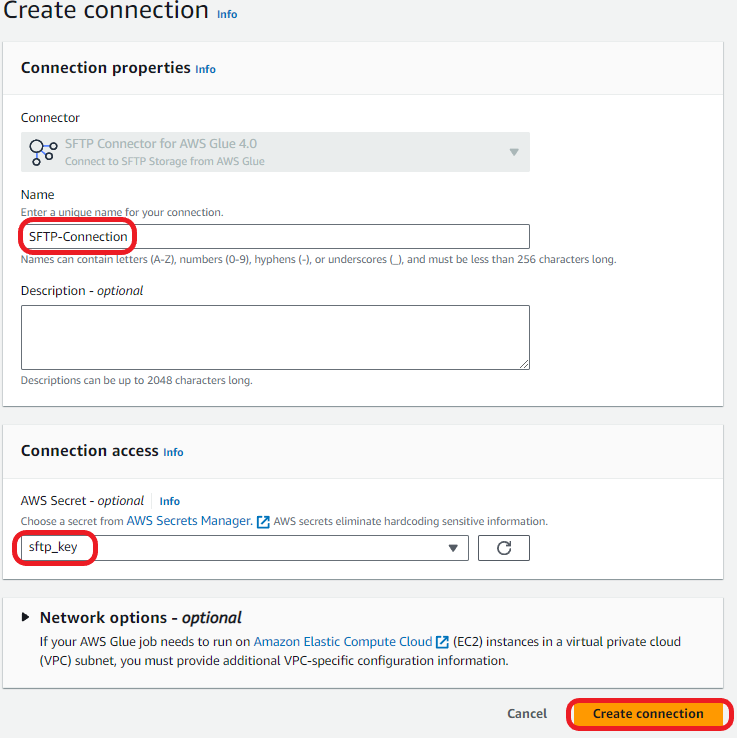
  1. Enter a name for the connection and then, under Connection access, choose the Secrets Manager secret you created for you SFTP server credentials.

finishing sftp connection

Create a connection to the VPC in AWS Glue

A data connection is used to establish network connectivity between the VPC and the AWS Glue job. To create the VPC connection, complete the following steps.

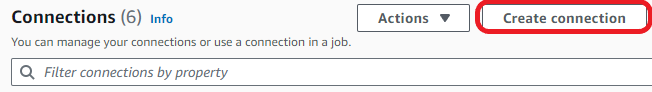
  1. On the AWS Glue console page, click on Data Connections location on the left side menu.
  2. Click the Create connection button in the Connections panel.

creating connection for VPC

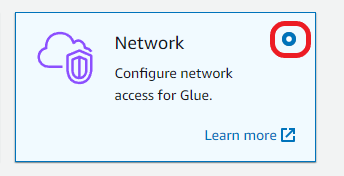
  1. Select Network

choosing network option

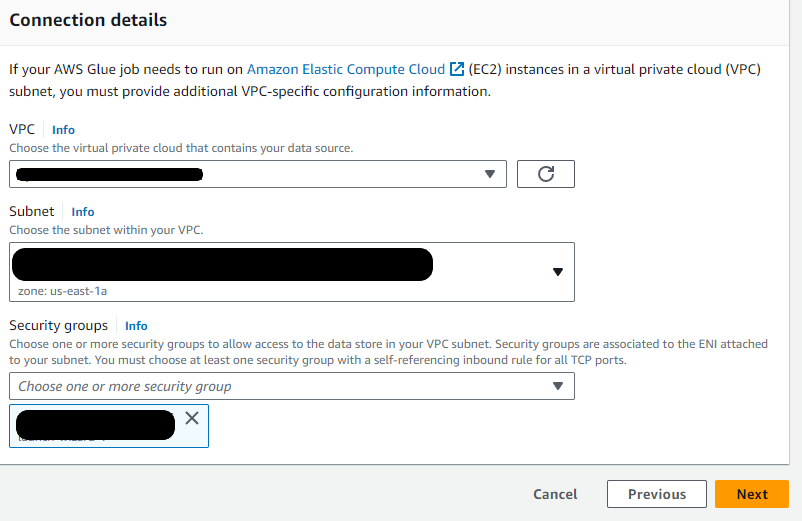
  1. Select the VPC, Subnet, and Security Group that your SFTP server resides in. Click Next.

choosing vpc, subnet, sg for connection

  1. Name the connection SFTP VPC Connect and then click

Deploy the solution

Now that we completed the prerequisites, we are going to setup the AWS Glue Studio job for this solution. We will create a glue studio job, add events and venue data from the SFTP server, carry out data transformations and load transformed data to s3.

Create your AWS Glue Studio job:

  1. On the AWS Glue console, under ETL Jobs in the navigation pane, choose Visual ETL.
  2. Select Visual ETL in the central pane.
  3. Choose the pencil icon to enter a name for your job.
  4. Choose the Job details tab.

choosing job details

  1. Scroll down to and select Advanced properties and expand.
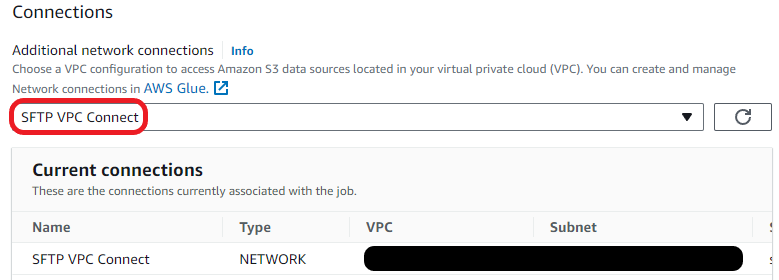
  2. Scroll to Connections and select SFTP VPC Connect.

choosing sftp vpc connection

  1. Choose Visual to go back to the workflow editor page.

Add the events data from the SFTP server as your first data set:

  1. Choose Add nodes and select SFTP Connector for AWS Glue 4.0 on the Sources
  2. Enter the following for Data source properties for:
    1. Connection: Select the connection to the SFTP server that you created in Create the connection to the SFTP server in AWS Glue.
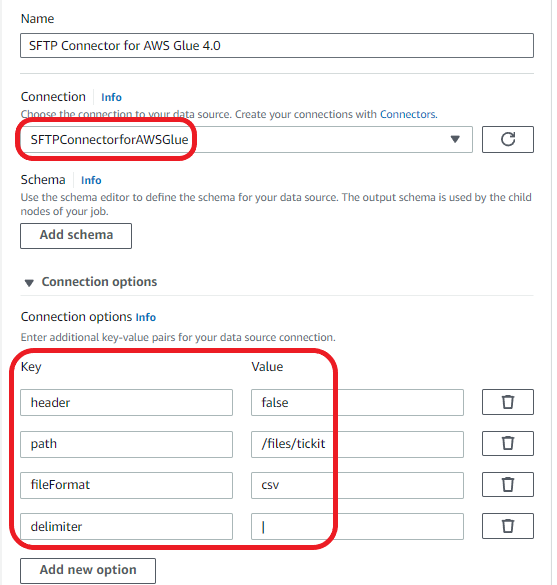
    2. Enter the following key-value pairs:
Key Value
header false
path /files (this should be the path to the event file in your SFTP server)
fileFormat csv
delimiter |

glue studio job configuration

Rename the columns of the Event dataset:

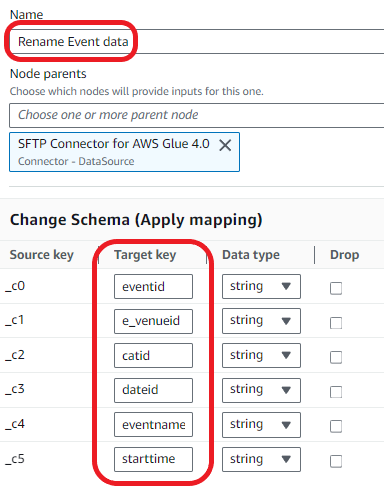
  1. Choose Add nodes and choose Change Schema on the Transforms
  2. Enter the following transform properties:
    1. For Name, enter Rename Event data.
    2. For Node parents, select SFTP Connector for AWS Glue 4.0.
    3. In the Change Schema section, map the source keys to the target keys:
      1. col0: eventid
      2. col1: e_venueid
      3. col2: catid
      4. col3: dateid
      5. col4: eventname
      6. col5: starttime

transforming event data

Add the venue_pipe.txt file from the SFTP site:

  1. Choose Add nodes and choose SFTP Connector for AWS Glue 4.0 on the Sources
  2. Enter the following for Data source properties for:
    1. Connection: Select the connection to the SFTP server that you created in Create the connection to the SFTP server in AWS Glue.
    2. Enter the following key-value pairs:
Key Value
header false
path /files (this should be the path to the venue file in your SFTP site)
fileFormat csv
delimiter |

Rename the columns of the venue dataset:

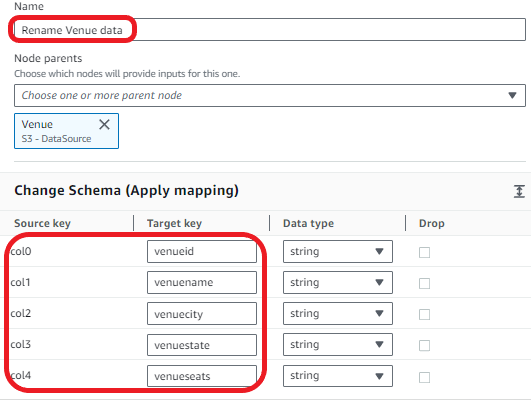
  1. Choose Add nodes and choose Change Schema on the Transforms
  2. Enter the following transform properties:
    1. For Name, enter Rename Venue data.
    2. For Node parents, select Venue.
    3. In the Change Schema section, map the source keys to the target keys:
      1. col0: venueid
      2. col1: venuename
      3. col2: venuecity
      4. col3: venuestate
      5. col4: venueseats

transforming venue data

Join the venue and event datasets.

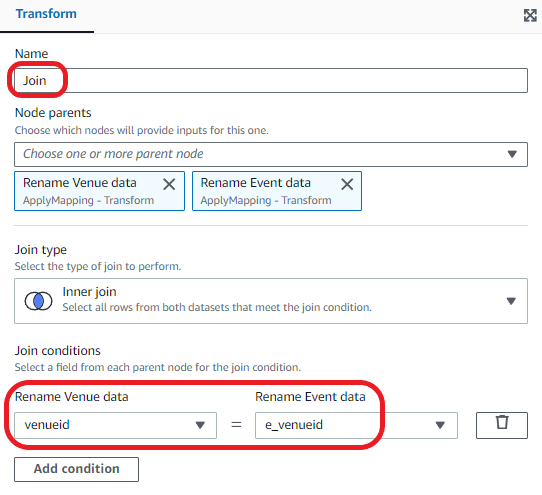
  1. Choose Add nodes and choose Join on the Transforms
  2. Enter the following transform properties:
    1. For Name, enter Join.
    2. For Node parents, select Rename Venue data and Rename Event data.
    3. For Join type¸ select Inner join.
    4. For Join conditions, select venueid for Rename Venue data and e_venueid for Rename Event data.

transform join venue and event

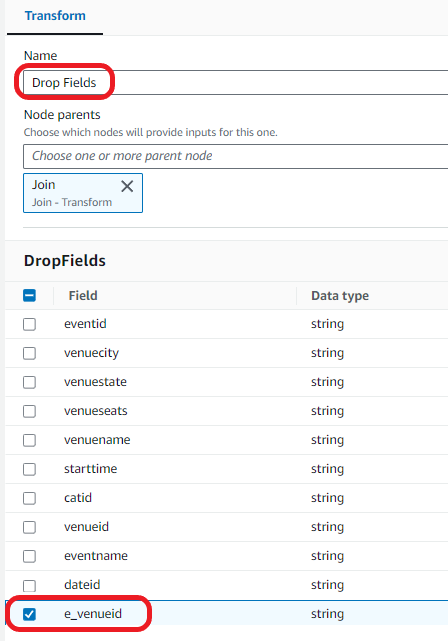
Drop the duplicate field:

  1. Choose Add nodes and choose Drop Fields on the Transforms
  2. Enter the following transform properties:
    1. For Name, enter Drop Fields.
    2. For Node parents, select Join.
    3. In the DropFields section, select e_venueid.

drop field transform

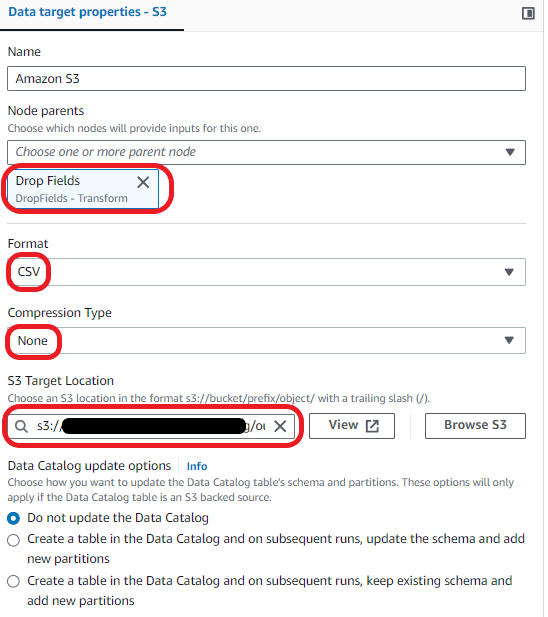
Load the data into your S3 bucket:

  1. Choose Add nodes and choose Amazon S3 from the Sources
  2. Enter the following transform properties:
    1. For Node parents, select Drop Fields.
    2. For Format, select CSV.
    3. For Compression Type, select None.
    4. For S3 Target Location, choose your S3 bucket and enter your desired file name followed by a slash (/).

loading data to s3 target

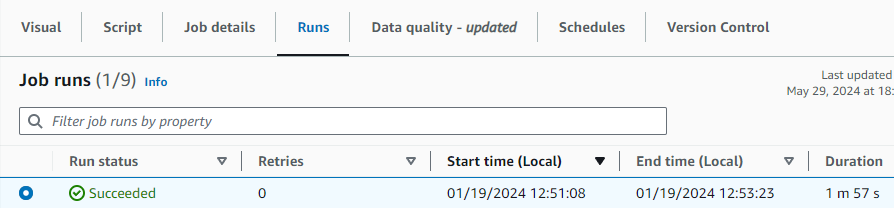
You can now save and run your AWS Glue visual ETL Job. Run the job and then go to the Runs tab to monitor its progress. After the job has completed, the Run status will change to Succeeded. The data will be in the target S3 bucket.

completed job

Clean up

To avoid incurring additional charges caused by resources created as part of this post, make sure you delete the items created in the AWS Account for this post:

  • Delete the Secrets Manager key created for the SFTP connector . credentials.
  • Delete the SFTP connector.
  • Unsubscribe from the SFTP Connector in AWS Marketplace.
  • Delete the data loaded to the Amazon S3 bucket and the bucket.
  • Delete the AWS Glue visual ETL job.

Conclusion

In this blog post, we demonstrated how to use the SFTP connector for AWS Glue to streamline the processing of data from SFTP servers into Amazon S3. This integration plays a pivotal role in enhancing your data analytics capabilities by offering an efficient and straightforward method to bring together disparate data sources. Whether your goal is to analyze SFTP server data for actionable insights, bolster your reporting mechanisms, or enrich your business intelligence tools, this connector ensures a more streamlined and cost-effective approach to achieving your data objectives.

For further details on the SFTP connector, see the SFTP Connector for Glue documentation.


About the Authors

Sean Bjurstrom is a Technical Account Manager in ISV accounts at Amazon Web Services, where he specializes in Analytics technologies and draws on his background in consulting to support customers on their analytics and cloud journeys. Sean is passionate about helping businesses harness the power of data to drive innovation and growth. Outside of work, he enjoys running and has participated in several marathons.

Seun Akinyosoye is a Sr. Technical Account Manager supporting public sector customer at Amazon Web Services. Seun has a background in analytics, data engineering which he uses to help customers achieve their outcomes and goals. Outside of work Seun enjoys spending time with his family, reading, traveling and supporting his favorite sports teams.

Vinod Jayendra is a Enterprise Support Lead in ISV accounts at Amazon Web Services, where he helps customers in solving their architectural, operational, and cost optimization challenges. With a particular focus on Serverless technologies, he draws from his extensive background in application development to deliver top-tier solutions. Beyond work, he finds joy in quality family time, embarking on biking adventures, and coaching youth sports team.

Kamen Sharlandjiev is a Sr. Big Data and ETL Solutions Architect, MWAA and AWS Glue ETL expert. He’s on a mission to make life easier for customers who are facing complex data integration and orchestration challenges. His secret weapon? Fully managed AWS services that can get the job done with minimal effort. Follow Kamen on LinkedIn to keep up to date with the latest MWAA and AWS Glue features and news!

Chris Scull is a Solutions Architect dealing in orchestration tools and modern cloud technologies. With two years of experience at AWS, Chris has developed an interest in Amazon Managed Workflows for Apache Airflow, which allows for efficient data processing and workflow management. Additionally, he is passionate about exploring the capabilities of GenAI with Bedrock, a platform for building generative AI applications on AWS.

Shengjie Luo is a Big data architect of Amazon Cloud Technology professional service team. Responsible for solutions consulting, architecture and delivery of AWS based data warehouse and data lake, and good at server-less computing, data migration, cloud data integration, data warehouse planning, data service architecture design and implementation.

Qiushuang Feng is a Solutions Architect at AWS, responsible for Enterprise customers’ technical architecture design, consulting, and design optimization on AWS Cloud services. Before joining AWS, Qiushuang worked in IT companies such as IBM and Oracle, and accumulated rich practical experience in development and analytics.

How AppsFlyer modernized their interactive workload by moving to Amazon Athena and saved 80% of costs

Post Syndicated from Michael Pelts original https://aws.amazon.com/blogs/big-data/how-appsflyer-modernized-their-interactive-workload-by-moving-to-amazon-athena-and-saved-80-of-costs/

This post is co-written with Nofar Diamant and Matan Safri from AppsFlyer. 

AppsFlyer develops a leading measurement solution focused on privacy, which enables marketers to gauge the effectiveness of their marketing activities and integrates them with the broader marketing world, managing a vast volume of 100 billion events every day. AppsFlyer empowers digital marketers to precisely identify and allocate credit to the various consumer interactions that lead up to an app installation, utilizing in-depth analytics.

Part of AppsFlyer’s offering is the Audiences Segmentation product, which allows app owners to precisely target and reengage users based on their behavior and demographics. This includes a feature that provides real-time estimation of audience sizes within specific user segments, referred to as the Estimation feature.

To provide users with real-time estimation of audience size, the AppsFlyer team originally used Apache HBase, an open-source distributed database. However, as the workload grew to 23 TB, the HBase architecture needed to be revisited to meet service level agreements (SLAs) for response time and reliability.

This post explores how AppsFlyer modernized their Audiences Segmentation product by using Amazon Athena. Athena is a powerful and versatile serverless query service provided by AWS. It’s designed to make it straightforward for users to analyze data stored in Amazon Simple Storage Service (Amazon S3) using standard SQL queries.

We dive into the various optimization techniques AppsFlyer employed, such as partition projection, sorting, parallel query runs, and the use of query result reuse. We share the challenges the team faced and the strategies they adopted to unlock the true potential of Athena in a use case with low-latency requirements. Additionally, we discuss the thorough testing, monitoring, and rollout process that resulted in a successful transition to the new Athena architecture.

Audiences Segmentation legacy architecture and modernization drivers

Audience segmentation involves defining targeted audiences in AppsFlyer’s UI, represented by a directed tree structure with set operations and atomic criteria as nodes and leaves, respectively.

The following diagram shows an example of audience segmentation on the AppsFlyer Audiences management console and its translation to the tree structure described, with the two atomic criteria as the leaves and the set operation between them as the node.

Audience segmentation tool and its translation to a tree structure

To provide users with real-time estimation of audience size, the AppsFlyer team used a framework called Theta Sketches, which is an efficient data structure for counting distinct elements. These sketches enhance scalability and analytical capabilities. These sketches were originally stored in the HBase database.

HBase is an open source, distributed, columnar database, designed to handle large volumes of data across commodity hardware with horizontal scalability.

Original data structure

In this post, we focus on the events table, the largest table initially stored in HBase. The table had the schema date | app-id | event-name | event-value | sketch and was partitioned by date and app-id.

The following diagram showcases the high-level original architecture of the AppsFlyer Estimations system.

High level architecture of the Estimations system

The architecture featured an Airflow ETL process that initiates jobs to create sketch files from the source dataset, followed by the importation of these files into HBase. Users could then use an API service to query HBase and retrieve estimations of user counts according to the audience segment criteria set up in the UI.

To learn more about the previous HBase architecture, see Applied Probability – Counting Large Set of Unstructured Events with Theta Sketches.

Over time, the workload exceeded the size for which HBase implementation was originally designed, reaching a storage size of 23 TB. It became apparent that in order to meet AppsFlyer’s SLA for response time and reliability, the HBase architecture needed to be revisited.

As previously mentioned, the focus of the use case entailed daily interactions by customers with the UI, necessitating adherence to a UI standard SLA that provides quick response times and the capability to handle a substantial number of daily requests, while accommodating the current data volume and potential future expansion.

Furthermore, due to the high cost associated with operating and maintaining HBase, the aim was to find an alternative that is managed, straightforward, and cost-effective, that wouldn’t significantly complicate the existing system architecture.

Following thorough team discussions and consultations with the AWS experts, the team concluded that a solution using Amazon S3 and Athena stood out as the most cost-effective and straightforward choice. The primary concern was related to query latency, and the team was particularly cautious to avoid any adverse effects on the overall customer experience.

The following diagram illustrates the new architecture using Athena. Notice that import-..-sketches-to-hbase and HBase were omitted, and Athena was added to query data in Amazon S3.

High level architecture of the Estimations system using Athena

Schema design and partition projection for performance enhancement

In this section, we discuss the process of schema design in the new architecture and different performance optimization methods that the team used including partition projection.

Merging data for partition reduction

In order to evaluate if Athena can be used to support Audiences Segmentation, an initial proof of concept was conducted. The scope was limited to events arriving from three app-ids (approximated 3 GB of data) partitioned by app-id and by date, using the same partitioning schema that was used in the HBase implementation. As the team scaled up to include the entire dataset with 10,000 app-ids for a 1-month time range (reaching an approximated 150 GB of data), the team started to see more slow queries, especially for queries that spanned over significant time ranges. The team dived deep and discovered that Athena spent significant time at the query planning stage due to a large number of partitions (7.3 million) that it loaded from the AWS Glue Data Catalog (for more information about using Athena with AWS Glue, see Integration with AWS Glue).

This led the team to examine partition indexing. Athena partition indexes provide a way to create metadata indexes on partition columns, allowing Athena to prune the data scan at the partition level, which can reduce the amount of data that needs to be read from Amazon S3. Partition indexing shortened the time of partition discovery in the query planning stage, but the improvement wasn’t substantial enough to meet the required query latency SLA.

As an alternative to partition indexing, the team evaluated a strategy to reduce partition number by reducing data granularity from daily to monthly. This method consolidated daily data into monthly aggregates by merging day-level sketches into monthly composite sketches using the Theta Sketches union capability. For example, taking a data of a month range, instead of having 30 rows of data per month, the team united those rows into a single row, effectively slashing the row count by 97%.

This method greatly decreased the time needed for the partition discovery phase by 30%, which initially required approximately 10–15 seconds, and it also reduced the amount of data that had to be scanned. However, the expected latency goals based on the UI’s responsiveness standards were still not ideal.

Furthermore, the merging process inadvertently compromised the precision of the data, leading to the exploration of other solutions.

Partition projection as an enhancement multiplier

At this point, the team decided to explore partition projection in Athena.

Partition projection in Athena allows you to improve query efficiency by projecting the metadata of your partitions. It virtually generates and discovers partitions as needed without the need for the partitions to be explicitly defined in the database catalog beforehand.

This feature is particularly useful when dealing with large numbers of partitions, or when partitions are created rapidly, as in the case of streaming data.

As we explained earlier, in this particular use case, each leaf is an access pattern being translated into a query that must contain date range, app-id, and event-name. This led the team to define the projection columns by using date type for the date range and injected type for app-id and event-name.

Rather than scanning and loading all partition metadata from the catalog, Athena can generate the partitions to query using configured rules and values from the query. This avoids the need to load and filter partitions from the catalog by generating them in the moment.

The projection process helped avoid performance issues caused by a high number of partitions, eliminating the latency from partition discovery during query runs.

Because partition projection eliminated the dependency between number of partitions and query runtime, the team could experiment with an additional partition: event-name. Partitioning by three columns (date, app-id, and event-name) reduced the amount of scanned data, resulting in a 10% improvement in query performance compared to the performance using partition projection with data partitioned only by date and app-id.

The following diagram illustrates the high-level data flow of sketch file creation. Focusing on the sketch writing process (write-events-estimation-sketches) into Amazon S3 with three partition fields caused the process to run twice as long compared to the original architecture, due to an increased number of sketch files (writing 20 times more sketch files to Amazon S3).

High level data flow of Sketch file creation

This prompted the team to drop the event-name partition and compromise on two partitions: date and app-id, resulting in the following partition structure:

s3://bucket/table_root/date=${day}/app_id=${app_id}

Using Parquet file format

In the new architecture, the team used Parquet file format. Apache Parquet is an open source, column-oriented data file format designed for efficient data storage and retrieval. Each Parquet file contains metadata such as minimum and maximum value of columns that allows the query engine to skip loading unneeded data. This optimization reduces the amount of data that needs to be scanned, because Athena can skip or quickly navigate through sections of the Parquet file that are irrelevant to the query. As a result, query performance improves significantly.

Parquet is particularly effective when querying sorted fields, because it allows Athena to facilitate predicate pushdown optimization and quickly identify and access the relevant data segments. To learn more about this capability in Parquet file format, see Understanding columnar storage formats.

Recognizing this advantage, the team decided to sort by event-name to enhance query performance, achieving a 10% improvement compared to non-sorted data. Initially, they tried partitioning by event-name to optimize performance, but this approach increased writing time to Amazon S3. Sorting demonstrated query time improvement without the ingestion overhead.

Query optimization and parallel queries

The team discovered that performance could be improved further by running parallel queries. Instead of a single query over a long window of time, multiple queries were run over shorter windows. Even though this increased the complexity of the solution, it improved performance by about 20% on average.

For instance, consider a scenario where a user requests the estimated size of app com.demo and event af_purchase between April 2024 and end of June 2024 (as illustrated earlier, the segmentation is defined by the user and then translated to an atomic leaf, which is then broken down to multiple queries depending on the date range). The following diagram illustrates the process of breaking down the initial 3-month query into two separate up to 60-day queries, running them simultaneously and then merging the results.

Splitting query by date range

Reducing results set size

In analyzing performance bottlenecks, examining the different types and properties of the queries, and analyzing the different stages of the query run, it became clear that specific queries were slow in fetching query results. This problem wasn’t rooted in the actual query run, but in data transfer from Amazon S3 at the GetQueryResults phase, due to query results containing a large number of rows (a single result can contain millions of rows).

The initial approach of handling multiple key-value permutations in a single sketch inflated the number of rows considerably. To overcome this, the team introduced a new event-attr-key field to separate sketches into distinct key-value pairs.

The final schema looked as follows:

date | app-id | event-name | event-attr-key | event-attr-value | sketch

This refactoring resulted in a drastic reduction of result rows, which significantly expedited the GetQueryResults process, markedly improving overall query runtime by 90%.

Athena query results reuse

To address a common use case in the Audiences Segmentation GUI where users often make subtle adjustments to their queries, such as adjusting filters or slightly altering time windows, the team used the Athena query results reuse feature. This feature improves query performance and reduces costs by caching and reusing the results of previous queries. This feature plays a pivotal role, particularly when taking into account the recent improvements involving the splitting of date ranges. The ability to reuse and swiftly retrieve results means that these minor—yet frequent—modifications no longer require a full query reprocessing.

As a result, the latency of repeated query runs was reduced by up to 80%, enhancing the user experience by providing faster insights. This optimization not only accelerates data retrieval but also significantly reduces costs because there’s no need to rescan data for every minor change.

Solution rollout: Testing and monitoring

In this section, we discuss the process of rolling out the new architecture, including testing and monitoring.

Solving Amazon S3 slowdown errors

During the solution testing phase, the team developed an automation process designed to assess the different audiences within the system, using the data organized within the newly implemented schema. The methodology involved a comparative analysis of results obtained from HBase against those derived from Athena.

While running these tests, the team examined the accuracy of the estimations retrieved and also the latency change.

In this testing phase, the team encountered some failures when running many concurrent queries at once. These failures were caused by Amazon S3 throttling due to too many GET requests to the same prefix produced by concurrent Athena queries.

In order to handle the throttling (slowdown errors), the team added a retry mechanism for query runs with an exponential back-off strategy (wait time increases exponentially with a random offset to prevent concurrent retries).

Rollout preparations

At first, the team initiated a 1-month backfilling process as a cost-conscious approach, prioritizing accuracy validation before committing to a comprehensive 2-year backfill.

The backfilling process included running the Spark job (write-events-estimation-sketches) in the desired time range. The job read from the data warehouse, created sketches from the data, and wrote them to files in the specific schema that the team defined. Additionally, because the team used partition projection, they could skip the process of updating the Data Catalog with every partition being added.

This step-by-step approach allowed them to confirm the correctness of their solution before proceeding with the entire historical dataset.

With confidence in the accuracy achieved during the initial phase, the team systematically expanded the backfilling process to encompass the full 2-year timeframe, assuring a thorough and reliable implementation.

Before the official release of the updated solution, a robust monitoring strategy was implemented to safeguard stability. Key monitors were configured to assess critical aspects, such as query and API latency, error rates, API availability.

After the data was stored in Amazon S3 as Parquet files, the following rollout process was designed:

  1. Keep both HBase and Athena writing processes running, stop reading from HBase, and start reading from Athena.
  2. Stop writing to HBase.
  3. Sunset HBase.

Improvements and optimizations with Athena

The migration from HBase to Athena, using partition projection and optimized data structures, has not only resulted in a 10% improvement in query performance, but has also significantly boosted overall system stability by scanning only the necessary data partitions. In addition, the transition to a serverless model with Athena has achieved an impressive 80% reduction in monthly costs compared to the previous setup. This is due to eliminating infrastructure management expenses and aligning costs directly with usage, thereby positioning the organization for more efficient operations, improved data analysis, and superior business outcomes.

The following table summarizes the improvements and the optimizations implemented by the team.

Area of Improvement Action Taken Measured Improvement
Athena partition projection Partition projection over the large number of partitions, avoiding limiting the number of partitions; partition by event_name and app_id Hundreds of percent improvement in query performance. This was the most significant improvement, which allowed the solution to be feasible.
Partitioning and sorting Partitioning by app_id and sorting event_name with daily granularity 100% improvement in jobs calculating the sketches. 5% latency in query performance.
Time range queries Splitting long time range queries into multiple queries running in parallel 20% improvement in query performance.
Reducing results set size Schema refactoring 90% improvement in overall query time.
Query result reuse Supporting Athena query results reuse 80% improvement in queries ran more than once in the given time.

Conclusion

In this post, we showed how Athena became the main component of the AppsFlyer Audiences Segmentation offering. We explored various optimization techniques such as data merging, partition projection, schema redesign, parallel queries, Parquet file format, and the use of the query result reuse.

We hope our experience provides valuable insights to enhance the performance of your Athena-based applications. Additionally, we recommend checking out Athena performance best practices for further guidance.


About the Authors

Nofar DiamantNofar Diamant is a software team lead at AppsFlyer with a current focus on fraud protection. Before diving into this realm, she led the Retargeting team at AppsFlyer, which is the subject of this post. In her spare time, Nofar enjoys sports and is passionate about mentoring women in technology. She is dedicated to shifting the industry’s gender demographics by increasing the presence of women in engineering roles and encouraging them to succeed.

Matan Safri Matan Safri is a backend developer focusing on big data in the Retargeting team at AppsFlyer. Before joining AppsFlyer, Matan was a backend developer in IDF and completed an MSC in electrical engineering, majoring in computers at BGU university. In his spare time, he enjoys wave surfing, yoga, traveling, and playing the guitar.

Michael PeltsMichael Pelts is a Principal Solutions Architect at AWS. In this position, he works with major AWS customers, assisting them in developing innovative cloud-based solutions. Michael enjoys the creativity and problem-solving involved in building effective cloud architectures. He also likes sharing his extensive experience in SaaS, analytics, and other domains, empowering customers to elevate their cloud expertise.

Orgad Kimchi Orgad Kimchi is a Senior Technical Account Manager at Amazon Web Services. He serves as the customer’s advocate and assists his customers in achieving cloud operational excellence focusing on architecture, AI/ML in alignment with their business goals.

Introducing AWS Glue Data Quality anomaly detection

Post Syndicated from Noah Soprala original https://aws.amazon.com/blogs/big-data/introducing-aws-glue-data-quality-anomaly-detection/

Thousands of organizations build data integration pipelines to extract and transform data. They establish data quality rules to ensure the extracted data is of high quality for accurate business decisions. These rules commonly assess the data based on fixed criteria reflecting the current business state. However, when the business environment changes, data properties shift, rendering these fixed criteria outdated and causing poor data quality.

For example, a data engineer at a retail company established a rule that validates daily sales must exceed a 1-million-dollar threshold. After a few months, daily sales surpassed 2 million dollars, rendering the threshold obsolete. The data engineer couldn’t update the rules to reflect the latest thresholds due to lack of notification and the effort required to manually analyze and update the rule. Later in the month, business users noticed a 25% drop in their sales. After hours of investigation, the data engineers discovered that an extract, transform, and load (ETL) pipeline responsible for extracting data from some stores had failed without generating errors. The rule with outdated thresholds continued to operate successfully without detecting this anomaly.

Also, breaks or gaps that significantly deviate from the seasonal pattern can sometimes point to data quality issues. For instance, retail sales may be highest on weekends and holiday seasons while relatively low on weekdays. Divergence from this pattern may indicate data quality issues such as missing data from a store or shifts in business circumstances. Data quality rules with fixed criteria can’t detect seasonal patterns because this requires advanced algorithms that can learn from past patterns and capture seasonality to detect deviations. You need the ability spot anomalies with ease, enabling you to proactively detect data quality issues and make confident business decisions.

To address these challenges, we are excited to announce the general availability of anomaly detection capabilities in AWS Glue Data Quality. In this post, we demonstrate how this feature works with an example. We provide an AWS Cloud Formation template to deploy this setup and experiment with this feature.

For completeness and ease of navigation, you can explore all the following AWS Glue Data Quality blog posts. This will help you understand all the other capabilities of AWS Glue Data Quality, in addition to anomaly detection.

Solution overview

For our use case, a data engineer wants to measure and monitor data quality of the New York taxi ride dataset. The data engineer knows about a few rules, but wants to monitor critical columns and be notified about any anomalies in these columns. These columns include fare amount, and the data engineer wants to be notified about any major deviations. Another attribute is the number of rides, which varies during peak hours, mid-day hours, and night hours. Also, as the city grows, there will be gradual increase in the number of rides overall. We use anomaly detection to help set up and maintain rules for this seasonality and growing trend.

We demonstrate this feature with the following steps:

  1. Deploy a CloudFormation template that will generate 7 days of NYC taxi data.
  2. Create an AWS Glue ETL job and configure the anomaly detection capability.
  3. Run the job for 6 days and explore how AWS Glue Data Quality learns from data statistics and detects anomalies.

Set up resources with AWS CloudFormation

This post includes a CloudFormation template for a quick setup. You can review and customize it to suit your needs. The template generates the following resources:

  • An Amazon Simple Storage Service (Amazon S3) bucket (anomaly-detection-blog-<account-id>-<region>)
  • An AWS Identity and Access Management (IAM) policy to associate with the S3 bucket (anomaly-detection-blog-<account-id>-<region>)
  • An IAM role with AWS Glue run permission as well as read and write permission on the S3 bucket (anomaly_detection_blog_GlueServiceRole)
  • An AWS Glue database to catalog the data (anomaly_detection_blog_db)
  • An AWS Glue visual ETL job to generate sample data (anomaly_detection_blog_data_generator_job)

To create your resources, complete the following steps:

  1. Launch your CloudFormation stack in us-east-1.
  2. Keep all settings as default.
  3. Select I acknowledge that AWS CloudFormation might create IAM resources and choose Create stack.
  4. When the stack is complete, copy the AWS Glue script to the S3 bucket anomaly-detection-blog-<account-id>-<region>.
  5. Open AWS CloudShell.
  6. Run the following command; replace account-id and region as appropriate:
    aws s3 cp s3://aws-blogs-artifacts-public/BDB-4485/scripts/anomaly_detection_blog_data_generator_job.py s3://anomaly-detection-blog-<account-id>-<region>/scripts/anomaly_detection_blog_data_generator_job.py

Run the data generator job

As part of the CloudFormation template, a data generator AWS Glue job is provisioned in your AWS account. Complete the following steps to run the job:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Choose the job
  3. Review the script on the Script
  4. On the Job details tab, verify the job run parameters in the Advanced section:
    1. bucket_name – The S3 bucket name where you want the data to be generated.
    2. bucket_prefix – The prefix in the S3 bucket.
    3. gluecatalog_database_name – The database name in the AWS Glue Data Catalog that was created by the CloudFormation template.
    4. gluecatalog_table_name – The table name to be created in the Data Catalog in the database.
  5. Choose Run to run this job.
  6. On the Runs tab, monitor the job until the Run status column shows as Succeeded.

When the job is complete, it will have generated the NYC taxi dataset for the date range of May 1, 2024, to May 7, 2024, in the specified S3 bucket and cataloged the table and partitions in the Data Catalog for year, month, day, and hour. This dataset contains 7 day of hourly rides that fluctuates between high and low on alternate days. For instance, on Monday, there are approximately 1,400 rides, on Tuesday around 700 rides, and this pattern continues. Of the 7 days, the first 5 days of data is non-anomalous. However, on the sixth day, an anomaly occurs where the number of rows jumps to around 2,200 and the fare_amount is set to an unusually high value of 95 for mid-day traffic.

Create an AWS Glue visual ETL job

Complete the following steps:

  1. On the AWS Glue console, create a new AWS Glue visual job named anomaly-detection-blog-visual.
  2. On the Job details tab, provide the IAM role created by the CloudFormation stack.
  3. On the Visual tab, add an S3 node for the data source.
  4. Provide the following parameters:
    1. For Database, choose anomaly_detection_blog_db.
    2. For Table, choose nyctaxi_raw.
    3. For Partition predicate, enter year==2024 AND month==5 AND day==1.
  1. Add the Evaluate Data Quality transform and add use the following rule for fare_amount:
    Rules = [
        ColumnValues "fare_amount" between 1 and 100
    ]

Because we’re still trying to understand the statistics on this metric, we start with a wide range rule, and after a few runs, we will analyze the results and fine-tune as needed.

Next, we add two analyzers: one for RowCount and another for distinct values of pulocationid.

  1. On the Anomaly detection tab, choose Add analyzer.
  2. For Statistics, enter RowCount.
  3. Add a second analyzer.
  4. For Statistics, enter DistinctValuesCount and for Columns, enter pulocationid.

Your final ruleset should look like the following code:

Rules = [
    ColumnValues "fare_amount" between 1 and 100
]
Analyzers = [
DistinctValuesCount "pulocationid",
RowCount
]
  1. Save the job.

We have now generated a synthetic NYC taxi dataset and authored an AWS Glue visual ETL job to read from this dataset and perform analysis with one rule and two analyzers.

Run and evaluate the visual ETL job

Before we run the job, let’s look at how anomaly detection works. In this example, we have configured one rule and two analyzers. Rules have thresholds to compare what good looks like. Sometimes, you might know the critical columns, but not know specific thresholds. Rules and analyzers gather data statistics or data profiles. In this example, AWS Glue Data Quality will gather four statistics (a ColumnValue rule will gather two statistics, namely minimum and maximum fare amount, and two analyzers will gather two statistics). After gathering three data points from three runs, AWS Glue Data Quality will predict the fourth run along with upper and lower bounds. It will then compare the predicted value with the actual value. When the actual value breaches the predicted upper or lower bounds, it will create an anomaly.

Let’s see this in action.

Run the job for 5 days and analyze results

Because the first 5 days of data is non-anomalous, it will set a baseline with seasonality for training the model. Complete the following steps to run the job five times, once for each day’s partition:

  1. Choose the S3 node on the Visual tab and go to its properties.
  2. Set the day field in the partition predicate to 1.
  3. Choose Run to run this job.
  4. Monitor the job on the Runs tab for Succeeded
  5. Repeat these steps four more times, each time incrementing the day field in the partition predicate. Run the jobs at more or less regular intervals to get a clean graph that simulates the automated scheduled pipeline.
  6. After five successful runs, go to the Data quality tab, where you should see the statistic gathered for fare_amount and RowCount.

The anomaly detection algorithm takes a minimum of three data points to learn and start predicting. After three runs, you may see multiple anomalies detected in your dataset. This is expected because every new trend is seen as an anomaly at first. As the algorithm processes more and more records, it learns from it and sets the upper and lower bounds on your data accurately. The upper and lower bound predictions are dependent on the interval between the job runs.

Also, we can observe that the data quality score is always 100% based on the generic fare_amount rule we set up. You can explore the statistics by choosing the View trends links for each of the metrics to deep dive into the values. For example, the following screenshot shows the values for minimum fare_amount over a set of runs.

The model has predicted the upper bound to be around 1.4 and the lower bound to be around 1.2 for the minimum statistic of the fare_amount metric. When these bounds are breached, it would be considered an anomaly.

Run the job for the sixth (anomalous) day and analyze results

For the sixth day, we process a file that has two known anomalies. With this run, you should see anomalies detected on the graph. Complete the following steps:

  1. Choose the S3 node on the Visual tab and go to its properties.
  2. Set the day field in the partition predicate to 6.
  3. Choose Run to run this job.
  4. Monitor the job on the Runs tab for Succeeded

You should see a screenshot as follows where two anomalies are detected as expected: one for fare_amount with a high value of 95 and one for RowCount with a value of 2776.

Notice that even though the fare_amount score was anomalous and high, the data quality score is still 100%. We will fix this later.

Let’s investigate the RowCount anomaly further. As shown in the following screenshot, if you expand the anomaly record, you can see how the prediction upper bound was breached to cause this anomaly.

Up until this point, we saw how a baseline was set for the model training and statistics collected. We also saw how an anomalous value in our dataset was flagged as an anomaly by the model.

Update data quality rules based on findings

Now that we understand the statistics, lets adjust our ruleset such that when the rules fail, the data quality score is impacted. We take rule recommendations from the anomaly detection feature and add them to the ruleset.

As shown earlier, when the anomaly is detected, it gives you rule recommendations to the right of the graph. For this case, the rule recommendation states the RowCount metric should be between 275.0–1966.0. Let’s update our visual job.

  1. Copy the rule under Rule Recommendations for RowCount.
  2. On the Visual tab, choose the Evaluate Data Quality node, go to its properties, and enter the rule in the rules editor.
  3. Repeat these steps for fare_amount.
  4. You can adjust your final ruleset to look as follows:
    Rules = [
        ColumnValues "fare_amount" <= 52, 
        RowCount between 100 and 1800
    ]
    Analyzers = [
    DistinctValuesCount "pulocationid",
    RowCount
    ]

  5. Save the job, but don’t run it yet.

So far, we have learned how to use statistics collected to adjust the rules and make sure our data quality score is accurate. But there is a problem—the anomalous values influence the model training, forcing the upper and lower bounds to adjust to the anomaly. We need to exclude those data points.

Exclude the RowCount anomaly

When an anomaly is detected in your dataset, the upper and lower bound prediction will adjust to it because it will assume it’s a seasonality by default. After investigation, if you believe that it is indeed an anomaly and not a seasonality, you should exclude the anomaly so it doesn’t impact future predictions.

Because our sixth run is an anomaly, you can complete the following steps to exclude it:

  1. On the Anomalies tab, select the anomaly row you want to exclude.
  2. On the Edit training inputs menu, choose Exclude anomaly.
  3. Choose Save and retrain.
  4. Choose the refresh icon.

If you need to view previous anomalous runs, navigate to the Data quality trend graph, hover over the anomaly data point, and choose View selected run results. This will take you to the job run on a new tab where you can follow the preceding steps to exclude the anomaly.

Alternatively, if you ran the job over a period of time and need to exclude multiple data points, you can do so from the Statistics tab:

  1. On the Data quality tab, go to the Statistics tab and choose View trends for RowCount.
  2. Select the value you want to exclude.
  3. On the Edit training inputs menu, choose Exclude anomaly.
  4. Choose Save and retrain.
  5. Choose the refresh icon.

It may take a few seconds to reflect the change.

The following figure shows how the model adjusted to the anomalies before exclusion.

The following figure shows how the model retrained itself after the anomalies were excluded.

Now that the predictions are adjusted, all future out-of-range values will be detected as anomalies again.

Now you can run the job for day 7, which has non-anomalous data, and explore the trends.

Add an anomaly detection rule

It can be challenging to modify the rule values with the growing business trends. For example, at some point in future, the NYC taxi rows will exceed the now anomalous RowCount value of 2200. As you run the job over a longer period of time, the model matures and fine-tunes itself to the incoming data. At that point, you can make anomaly detection a rule by itself so you don’t have to update the values and can stop the jobs or decrease the data quality score. When there is an anomaly in the dataset, it means that the quality of the data is not good and the data quality score should reflect that. Let’s add a DetectAnomalies rule for the RowCount metric.

  1. On the Visual tab, choose the Evaluate Data Quality node.
  2. For Rule types, search for and choose DetectAnomalies, then add the rule.

Your final ruleset should look like the following screenshot. Notice that you don’t have any values for RowCount.

This is the real power of anomaly detection in your ETL pipeline.

Seasonality use case

The following screenshot shows an example of a trend with a more in-depth seasonality. The NYC taxi dataset has a varying number of rides throughout the day depending on peak hours, mid-day hours, and night hours. The following anomaly detection job ran on the current timestamp every hour to capture the seasonality of the day, and the upper and lower bounds have adjusted to this seasonality. When the number of rides drops unexpectedly within that seasonality trend, it is detected as an anomaly.

We saw how a data engineer can build anomaly detection into their pipeline for the incoming flow of data being processed at regular interval. We also learned how you can make anomaly detection a rule after the model is mature and fail the job, if an anomaly is detected, to avoid redundant downstream processing.

Clean up

To clean up your resources, complete the following steps:

  1. On the Amazon S3 console, empty the S3 bucket created by the CloudFormation stack.
  2. On the AWS Glue console, delete the anomaly-detection-blog-visual AWS Glue job you created.
  3. If you deployed the CloudFormation stack, delete the stack on the AWS CloudFormation console.

Conclusion

This post demonstrated the new anomaly detection feature in AWS Glue Data Quality. Although data quality static and dynamic rules are very useful, they can’t capture data seasonality and how data changes as your business evolves. A machine learning model supporting anomaly detection can understand these complex changes and inform you of anomalies in the dataset. Also, the recommendations provided can help you author accurate data quality rules. You can also enable anomaly detection as a rule after the model has been trained over a longer period of time on a sufficient amount of data.

To learn more about AWS Glue Data Quality, check out AWS Glue Data Quality. If you have any comments or feedback, leave them in the comments section.


About the authors

Noah Soprala is a Solutions Architect based out of Dallas. He is a trusted advisor to his customers in the ISV industry and helps them build innovative solutions using AWS technologies. Noah has over 20+ years of experience in consulting, development and solution delivery.

Shovan Kanjilal is a Senior Analytics and Machine Learning Architect with Amazon Web Services. He is passionate about helping customers build scalable, secure and high-performance data solutions in the cloud.

Shiv Narayanan is a Technical Product Manager for AWS Glue’s data management capabilities like data quality, sensitive data detection and streaming capabilities. Shiv has over 20 years of data management experience in consulting, business development and product management.

Jesus Max Hernandez is a Software Development Engineer at AWS Glue. He joined the team after graduating from The University of Texas at El Paso, and the majority of his work has been in frontend development. Outside of work, you can find him practicing guitar or playing flag football.

Tyler McDaniel is a software development engineer on the AWS Glue team with diverse technical interests, including high-performance computing and optimization, distributed systems, and machine learning operations. He has eight years of experience in software and research roles.

Andrius Juodelis is a Software Development Engineer at AWS Glue with a keen interest in AI, designing machine learning systems, and data engineering.

Build a real-time analytics solution with Apache Pinot on AWS

Post Syndicated from Raj Ramasubbu original https://aws.amazon.com/blogs/big-data/build-a-real-time-analytics-solution-with-apache-pinot-on-aws/

Online Analytical Processing (OLAP) is crucial in modern data-driven apps, acting as an abstraction layer connecting raw data to users for efficient analysis. It organizes data into user-friendly structures, aligning with shared business definitions, ensuring users can analyze data with ease despite changes. OLAP combines data from various data sources and aggregates and groups them as business terms and KPIs. In essence, it’s the foundation for user-centric data analysis in modern apps, because it’s the layer that translates technical assets into business-friendly terms that enable users to extract actionable insights from data.

Real-time OLAP

Traditionally, OLAP datastores were designed for batch processing to serve internal business reports. The scope of data analytics has grown, and more user personas are now seeking to extract insights themselves. These users often prefer to have direct access to the data and the ability to analyze it independently, without relying solely on scheduled updates or reports provided at fixed intervals. This has led to the emergence of real-time OLAP solutions, which are particularly relevant in the following use cases:

  • User-facing analytics – Incorporating analytics into products or applications that consumers use to gain insights, sometimes referred to as data products.
  • Business metrics – Providing KPIs, scorecards, and business-relevant benchmarks.
  • Anomaly detection – Identifying outliers or unusual behavior patterns.
  • Internal dashboards – Providing analytics that are relevant to stakeholders across the organization for internal use.
  • Queries – Offering subsets of data to users based on their roles and security levels, allowing them to manipulate data according to their specific requirements.

Overview of Apache Pinot

Building these capabilities in real time means that real-time OLAP solutions have stricter SLAs and larger scalability requirements than traditional OLAP datastores. Accordingly, a purpose-built solution is needed to address these new requirements.

Apache Pinot is an open source real-time distributed OLAP datastore designed to meet these requirements, including low latency (tens of milliseconds), high concurrency (hundreds of thousands of queries per second), near real-time data freshness, and handling petabyte-scale data volumes. It ingests data from both streaming and batch sources and organizes it into logical tables distributed across multiple nodes in a Pinot cluster, ensuring scalability.

Pinot provides functionality similar to other modern big data frameworks, supporting SQL queries, upserts, complex joins, and various indexing options.

Pinot has been tested at very large scale in large enterprises, serving over 70 LinkedIn data products, handling over 120,000 Queries Per Second (QPS), ingesting over 1.5 million events per second, and analyzing over 10,000 business metrics across over 50,000 dimensions. A notable use case is the user-facing Uber Eats Restaurant Manager dashboard, serving over 500,000 users with instant insights into restaurant performance.

Pinot clusters are designed for high availability, horizontal scalability, and live configuration changes without impacting performance. To that end, Pinot is architected as a distributed datastore to enable all of the above requirements, and utilizes similar architectural constructs as Apache Kafka and Apache Hadoop in its design.

Solution overview

In this, we will provide a step-by-step guide showing you how you can build a real-time OLAP datastore on Amazon Web Services (AWS) using Apache Pinot on Amazon Elastic Compute Cloud (Amazon EC2) and do near real-time visualization using Tableau. You can use Apache Pinot for batch processing use cases as well but, in this post, we will focus on a near real-time analytics use case.

You can use Amazon Managed Service for Apache Flink service. The objective in the preceding figure is to ingest streaming data into Pinot, where it can perform.

Blog post architecture

The objective in the preceding figure is to ingest streaming data into Pinot, where it can perform aggregations, update current data models, and serve OLAP queries in real time to consuming users and applications, which in this case is a user-facing Tableau dashboard.

The data flow as follows:

  • Data is ingested from a real-time source, such as clickstream data from a website. For the purposes of this post, we will use the Amazon Kinesis Data Generator to simulate the production of events.
  • Events are captured in a streaming storage platform such as or Amazon Managed Streaming for Apache Kafka (MSK) for downstream consumption.
  • The events are then ingested into the real-time server within Apache Pinot, which is used to process data coming from streaming sources, such as MSK and KDS. Apache Pinot consists of logical tables, which are partitioned into segments. Due to the time sensitive nature of streaming, events are directly written into memory as consuming segments, which can be thought of as parts of an active table that are continuously ingesting new data. Consuming segments are available for query processing immediately, thereby enabling low latency and high data freshness.
  • After the segments reach a threshold in terms of time or number of rows, they are moved into Amazon Simple Storage Service (Amazon S3), which serves as deep storage for the Apache Pinot cluster. Deep storage is the permanent location for segment files. Segments used for batch processing are also stored there.
  • In parallel, the Pinot controller tracks the metadata of the cluster and performs actions required to keep the cluster in an ideal state. Its primary function is to orchestrate cluster resources as well as manage connections between resources within the cluster and data sources outside of it. Under the hood, the controller uses Apache Helix to manage cluster state, failover, distribution, and scalability and Apache Zookeeper to handles distributed coordination functions such as leader election, locks, queue management, and state tracking.
  • To enable the distributed aspect of the Pinot architecture, the broker accepts queries from the clients and forwards them to servers and collects the results and sends them back. The broker manages and optimizes the queries, distributes them across the servers, combines the results, and returns the result set. The broker sends the request to the right segments on the right servers, optimizes segment pruning, and splits the queries across servers appropriately. The results of each query are then merged and sent back to the requesting client.
  • The results of the queries are updated in real time in the Tableau dashboard.

To ensure high availability, the solution deploys application load balancers for the brokers and servers. We can access the Apache Pinot UI using the controller load balancer and use it to run queries and monitor the Apache Pinot cluster

Let’s start to deploy this solution and perform near real-time visualizations using Apache Pinot and Tableau.

Prerequisites

Before you get started, make sure you have the following prerequisites:

Deploy the Apache Pinot solution using the AWS CDK

The AWS CDK is an open source project that you can use to define your cloud infrastructure using familiar programming languages. It uses high-level constructs to represent AWS components to simplify the build process. In this post, we use TypeScript and Python to define the cloud infrastructure.

  1. First, bootstrap the AWS CDK. This sets up the resources required by the AWS CDK to deploy into the AWS account. This step is only required if you haven’t used the AWS CDK in the deployment account and Region. The format for the bootstrap command is cdk bootstrap aws://<account-id>/<aws-region>.

In the following example, I’m running a bootstrap command for a fictitious AWS account with ID 123456789000 and us-east-1 N.Virginia Region:

cdk bootstrap aws://123456789000/us-east-1

Bootstrap command

  1. Next, clone the GitHub repository and install all the dependencies from package.json by running the following commands from the root of the cloned repository.
    git clonehttps://github.com/aws-samples/near-realtime-apache-pinot-workshop
    
    cd near-realtime-apache-pinot-workshop
    
    npm i

  2. Deploy the AWS CDK stack to create the AWS Cloud infrastructure by running the following command and enter y when prompted. Enter the IP address that you want to use to access the Apache Pinot controller and broker in /32 subnet mask format.
    cdk deploy --parameters IpAddress="<YOUR-IP-ADDRESS-IN-/32-SUBNET-MASK-FORMAT>"

Deployment of the AWS CDK stack takes approximately 10–12 minutes. You should see a stack deployment message that will display the creation of AWS objects, followed by the deployment time, the Stack ARN, and the total time, similar to the following screenshot:

CDK deployment screenshot

  1. Now, you can get the Apache Pinot controller Application Load Balancer (ALB) DNS name from the Copy the value for ControllerDNSUrl.
  2. Launch a browser session and paste the DNS name to see the Apache Pinot controller—it should look like the following screenshot, where you will see:
    • Number of controllers, brokers, servers, minions, tenants, and tables
    • List of tenants
    • List of controllers
    • List of brokers

Pinot management console

Near real-time visualization using Tableau

Now that we have provisioned all AWS Cloud resources, we will stream some sample web transactions to a Kinesis data stream and visualize the data in near real time from Tableau Desktop.

You can follow these steps to open the Tableau workbook to visualize

  1. Download the Tableau workbook to your local machine and open the workbook from Tableau Desktop.
  2. Get the DNS name for Apache Pinot broker’s Application Load Balancer DNS name from the CloudFormation console. Choose Stacks, select the ApachePinotSolutionStack, and then choose Outputs and copy the value for BrokerDNSUrl.
  3. Choose Edit connection and enter the URL in the following format:
    jdbc:pinot://<Apache-Pinot-Controller-DNS-Name>?brokers=<Apache-Pinot-Broker-DNS-Name>

  4. Enter admin for both the username and password.
  5. Access the KDG tool by following the instructions. Use the record template that follows to send sample web transactions data to Kinesis Data streams called pinot-stream by choosing Send dataas shown in the following screenshot. Stop sending data after sending a handful of records by choosing Stop sending data to Kinesis.
{
"userID" : "{{random.number(
{
"min":1,
"max":100
}
)}}",
"productName" : "{{commerce.productName}}",
"color" : "{{commerce.color}}",
"department" : "{{commerce.department}}",
"product" : "{{commerce.product}}",
"campaign" : "{{random.arrayElement(
["BlackFriday","10Percent","NONE"]
)}}",
"price" : {{random.number(
{   "min":10,
"max":150
}
)}},
"creationTimestamp" : "{{date.now("YYYY-MM-DD hh:mm:ss")}}"
}

Kinesis Data Generator configuration

You should be able to see the web transactions data in Tableau Desktop as shown in the following screenshot.

Clean up

To clean up the AWS resources you created:

  1. Disable termination protection on the following EC2 instances by going to the Amazon EC2 console and choosing Instance from the navigation pane. Choose Actions, Instance Settings, and then Change termination protection and clear the Termination protection checkbox.
    • ApachePinotSolutionStack/bastionHost
    • ApachePinotSolutionStack/zookeeperNode1
    • ApachePinotSolutionStack/zookeeperNode2
    • ApachePinotSolutionStack/zookeeperNode3
  2. Run the following command from the cloned GitHub repo and enter y when prompted.
    cdk destroy

Scaling the solution to production

The example in this post uses minimal resources to demonstrate functionality. Taking this to production requires a higher level of scalability. The solution provides autoscaling policies for independently scaling brokers and servers in and out, allowing the Apache Pinot custer to scale based on CPU requirements.

When autoscaling is initiated, the solution will invoke an AWS Lambda Function, to run the logic needed to add or remove brokers and servers in Apache Pinot.

In Apache Pinot, tables are tagged with an identifier that’s used for routing queries to the appropriate servers. When creating a table, you can specify a table name and optionally tag it. This is useful when you want to route queries to specific servers or build a multi-tenant Apache Pinot cluster. However, tagging adds additional considerations when removing brokers or servers. You need to make sure that neither have any active tables or tags associated with them. And when adding new components, rebalance the segments, so you can use the new brokers and servers.

Therefore, when scaling is needed in the solution, the autoscaling policy will invoke a Lambda function that either rebalances the segments of the tables when you add a new broker or server, or removes any tags associated with the broker or server you remove from the cluster.

Summary

Just like you would commonly use a distributed NoSQL datastore to serve a mobile application that requires low latency, high concurrency, high data freshness, high data volume, and high throughput, a distributed real-time OLAP datastore like Apache Pinot is purpose-built for achieving the same requirements for the analytics workload within your user-facing application. In this post, we walked you through how to deploy a scalable Apache Pinot-based near real-time user facing analytics solution on AWS. If you have any questions or suggestions, write to us in the comments section


About the authors

Raj RamasubbuRaj Ramasubbu is a Senior Analytics Specialist Solutions Architect focused on big data and analytics and AI/ML with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS. Raj provided technical expertise and leadership in building data engineering, big data analytics, business intelligence, and data science solutions for over 18 years prior to joining AWS. He helped customers in various industry verticals like healthcare, medical devices, life science, retail, asset management, car insurance, residential REIT, agriculture, title insurance, supply chain, document management, and real estate.

Francisco MorilloFrancisco Morillo is a Streaming Solutions Architect at AWS. Francisco works with AWS customers, helping them design real-time analytics architectures using AWS services, supporting Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink.

Ismail Makhlouf is a Senior Specialist Solutions Architect for Data Analytics at AWS. Ismail focuses on architecting solutions for organizations across their end-to-end data analytics estate, including batch and real-time streaming, big data, data warehousing, and data lake workloads. He primarily partners with airlines, manufacturers, and retail organizations to support them to achieve their business objectives with well-architected data platforms.

Hardening the RAG chatbot architecture powered by Amazon Bedrock: Blueprint for secure design and anti-pattern migration

Post Syndicated from Magesh Dhanasekaran original https://aws.amazon.com/blogs/security/hardening-the-rag-chatbot-architecture-powered-by-amazon-bedrock-blueprint-for-secure-design-and-anti-pattern-migration/

This blog post demonstrates how to use Amazon Bedrock with a detailed security plan to deploy a safe and responsible chatbot application. In this post, we identify common security risks and anti-patterns that can arise when exposing a large language model (LLM) in an application. Amazon Bedrock is built with features you can use to mitigate vulnerabilities and incorporate secure design principles. This post highlights architectural considerations and best practice strategies to enhance the reliability of your LLM-based application.

Amazon Bedrock unleashes the fusion of generative artificial intelligence (AI) and LLMs, empowering you to craft impactful chatbot applications. As with technologies handling sensitive data and intellectual property, it’s crucial that you prioritize security and adopt a robust security posture. Without proper measures, these applications can be susceptible to risks such as prompt injection, information disclosure, model exploitation, and regulatory violations. By proactively addressing these security considerations, you can responsibly use Amazon Bedrock foundation models and generative AI capabilities.

The chatbot application use case represents a common pattern in enterprise environments, where businesses want to use the power of generative AI foundation models (FMs) to build their own applications. This falls under the Pre-trained models category of the Generative AI Security Scoping Matrix. In this scope, businesses directly integrate with FMs like Anthropic’s Claude through Amazon Bedrock APIs to create custom applications, such as customer support Retrieval Augmented Generation (RAG) chatbots, content generation tools, and decision support systems.

This post provides a comprehensive security blueprint for deploying chatbot applications that integrate with Amazon Bedrock, enabling the responsible adoption of LLMs and generative AI in enterprise environments. We outline mitigation strategies through secure design principles, architectural considerations, and best practices tailored to the challenges of integrating LLMs and generative AI capabilities.

By following the guidance in this post, you can proactively identify and mitigate risks associated with deploying and operating chatbot applications that integrate with Amazon Bedrock and use generative AI models. The guidance can help you strengthen the security posture, protect sensitive data and intellectual property, maintain regulatory compliance, and responsibly deploy generative AI capabilities within your enterprise environments.

This post contains the following high-level sections:

Chatbot application architecture overview

The chatbot application architecture described in this post represents an example implementation that uses various AWS services and integrates with Amazon Bedrock and Anthropic’s Claude 3 Sonnet LLM. This baseline architecture serves as a foundation to understand the core components and their interactions. However, it’s important to note that there can be multiple ways for customers to design and implement a chatbot architecture that integrates with Amazon Bedrock, depending on their specific requirements and constraints. Regardless of the implementation approach, it’s crucial to incorporate appropriate security controls and follow best practices for secure design and deployment of generative AI applications.

The chatbot application allows users to interact through a frontend interface and submit prompts or queries. These prompts are processed by integrating with Amazon Bedrock, which uses the Anthropic Claude 3 Sonnet LLM and a knowledge base built from ingested data. The LLM generates relevant responses based on the prompts and retrieved context from the knowledge base. While this baseline implementation outlines the core functionality, it requires incorporating security controls and following best practices to mitigate potential risks associated with deploying generative AI applications. In the subsequent sections, we discuss security anti-patterns that can arise in such applications, along with their corresponding mitigation strategies. Additionally, we present a secure and responsible architecture blueprint for the chatbot application powered by Amazon Bedrock.

Figure 1: Baseline chatbot application architecture using AWS services and Amazon Bedrock

Figure 1: Baseline chatbot application architecture using AWS services and Amazon Bedrock

Components in the chatbot application baseline architecture

The chatbot application architecture uses various AWS services and integrates with the Amazon Bedrock service and Anthropic’s Claude 3 Sonnet LLM to deliver an interactive and intelligent chatbot experience. The main components of the architecture (as shown in Figure 1) are:

  1. User interaction layer:
    Users interact with the chatbot application through the Streamlit frontend (3), a Python-based open-source library, used to build the user-friendly and interactive interface.
  2. Amazon Elastic Container Service (Amazon ECS) on AWS Fargate:
    A fully managed and scalable container orchestration service that eliminates the need to provision and manage servers, allowing you to run containerized applications without having to manage the underlying compute infrastructure.
  3. Application hosting and deployment:
    The Streamlit application (3) components are hosted and deployed on Amazon ECS on AWS Fargate (2), maintaining scalability and high availability. This architecture represents the application and hosting environment in an independent virtual private cloud (VPC) to promote a loosely-coupled architecture. The Streamlit frontend can be replaced with your organization’s specific frontend and quickly integrated with the backend Amazon API Gateway in the VPC. An application load balancer is used to distribute traffic to the Streamlit application instances.
  4. API Gateway driven Lambda Integration:
    In this example architecture, instead of directly invoking the Amazon Bedrock service from the frontend, an API Gateway backed by an AWS Lambda function (5) is used as an intermediary layer. This approach promotes better separation of concerns, scalability, and secure access to Amazon Bedrock by limiting direct exposure from the frontend.
  5. Lambda:
    Lambda provides highly scalable, short-term serverless compute. Here, the requests from Streamlit are processed. First, the history of the user’s session is retrieved from Amazon DynamoDB (6). Second, the user’s question, history, and the context are formatted into a prompt template and queried against Amazon Bedrock with the knowledge base, employing retrieval augmented generation (RAG).
  6. DynamoDB:
    DynamoDB is responsible for storing and retrieving chat history, conversation history, recommendations, and other relevant data using the Lambda function.
  7. Amazon S3:
    Amazon Simple Storage Services (Amazon S3) is a data storage service and is used here for storing data artifacts that are ingested into the knowledge base.
  8. Amazon Bedrock:
    Amazon Bedrock plays a central role in the architecture. It handles the questions posed by the user using Anthropic Claude 3 Sonnet LLM (9) combined with a previously generated knowledge base (10) of the customer’s organization-specific data.
  9. Anthropic Claude 3 Sonnet:
    Anthropic Claude 3 Sonnet is the LLM used to generate tailored recommendations and responses based on user inputs and the context retrieved from the knowledge base. It’s part of the text analysis and generation module in Amazon Bedrock.
  10. Knowledge base and data ingestion:
    Relevant documents classified as public are ingested from Amazon S3 (9) into in an Amazon Bedrock knowledge base. Knowledge bases are backed by Amazon OpenSearch Service. Amazon Titan Embeddings (10) are used to generate the vector embeddings database of the documents. Storing the data as vector embeddings allows for semantic similarity searching of the documents to retrieve the context of the question posed by the user (RAG). By providing the LLM with context in addition to the question, there’s a much higher chance of getting a useful answer from the LLM.

Comprehensive logging and monitoring strategy

This section outlines a comprehensive logging and monitoring strategy for the Amazon Bedrock-powered chatbot application, using various AWS services to enable centralized logging, auditing, and proactive monitoring of security events, performance metrics, and potential threats.

  1. Logging and auditing:
    • AWS CloudTrail: Logs API calls made to Amazon Bedrock, including InvokeModel requests, as well as information about the user or service that made the request.
    • AWS CloudWatch Logs: Captures and analyzes Amazon Bedrock invocation logs, user prompts, generated responses, and errors or warnings encountered during the invocation process.
    • Amazon OpenSearch Service: Logs and indexes data related to the OpenSearch integration, context data retrievals, and knowledge base operations.
    • AWS Config: Monitors and audits the configuration of resources related to the chatbot application and Amazon Bedrock service, including IAM policies, VPC settings, encryption key management, and other resource configurations.
  2. Monitoring and alerting:
    • AWS CloudWatch: Monitors metrics specific to Amazon Bedrock, such as the number of model invocations, latency of invocations, and error metrics (client-side errors, server-side errors, and throttling). Configures targeted CloudWatch alarms to proactively detect and respond to anomalies or issues related to Bedrock invocations and performance.
    • AWS GuardDuty: Continuously monitors CloudTrail logs for potential threats and unauthorized activity within the AWS environment.
    • AWS Security Hub: Provides centralized security posture management and compliance checks.
    • Amazon Security Lake: Provides a centralized data lake for log analysis; is integrated with CloudTrail and SecurityHub.
  3. Security information and event management integration:
    • Integrate with security information and event management (SIEM) solutions for centralized log management, real-time monitoring of security events, and correlation of logging data from multiple sources (CloudTrail, CloudWatch Logs, OpenSearch Service, and so on).
  4. Continuous improvement:
    • Regularly review and update logging and monitoring configurations, alerting thresholds, and integration with security solutions to address emerging threats, changes in application requirements, or evolving best practices.

Security anti-patterns and mitigation strategies

This section identifies and explores common security anti-patterns associated with the Amazon Bedrock chatbot application architecture. By recognizing these anti-patterns early in the development and deployment phases, you can implement effective mitigation strategies and fortify your security posture.

Addressing security anti-patterns in the Amazon Bedrock chatbot application architecture is crucial for several reasons:

  1. Data protection and privacy: The chatbot application processes and generates sensitive data, including personal information, intellectual property, and confidential business data. Failing to address security anti-patterns can lead to data breaches, unauthorized access, and potential regulatory violations.
  2. Model integrity and reliability: Vulnerabilities in the chatbot application can enable bad actors to manipulate or exploit the underlying generative AI models, compromising the integrity and reliability of the generated outputs. This can have severe consequences, particularly in decision-support or critical applications.
  3. Responsible AI deployment: As the adoption of generative AI models continues to grow, it’s essential to maintain responsible and ethical deployment practices. Addressing security anti-patterns is crucial for maintaining trust, transparency, and accountability in the chatbot application powered by AI models.
  4. Compliance and regulatory requirements: Many industries and regions have specific regulations and guidelines governing the use of AI technologies, data privacy, and information security. Addressing security anti-patterns is a critical step towards adhering to and maintaining compliance for the chatbot application.

The security anti-patterns that are covered in this post include:

  1. Lack of secure authentication and access controls
  2. Insufficient input validation and sanitization
  3. Insecure communication channels
  4. Inadequate prompt and response logging, auditing, and non-repudiation
  5. Insecure data storage and access controls
  6. Failure to secure FMs and generative AI components
  7. Lack of responsible AI governance and ethics
  8. Lack of comprehensive testing and validation

Anti-pattern 1: Lack of secure authentication and access controls

In a generative AI chatbot application using Amazon Bedrock, a lack of secure authentication and access controls poses significant risks to the confidentiality, integrity, and availability of the system. Identity spoofing and unauthorized access can enable threat actors to impersonate legitimate users or systems, gain unauthorized access to sensitive data processed by the chatbot application, and potentially compromise the integrity and confidentiality of the customer’s data and intellectual property used by the application.

Identity spoofing and unauthorized access are important areas to address in this architecture, as the chatbot application handles user prompts and responses, which may contain sensitive information or intellectual property. If a threat actor can impersonate a legitimate user or system, they can potentially inject malicious prompts, retrieve confidential data from the knowledge base, or even manipulate the responses generated by the Anthropic Claude 3 LLM integrated with Amazon Bedrock.

Anti-pattern examples

  • Exposing the Streamlit frontend interface or the API Gateway endpoint without proper authentication mechanisms, potentially allowing unauthenticated users to interact with the chatbot application and inject malicious prompts.
  • Storing or hardcoding AWS access keys or API credentials in the application code or configuration files, increasing the risk of credential exposure and unauthorized access to AWS services like Amazon Bedrock or DynamoDB.
  • Implementing weak or easily guessable passwords for administrative or service accounts with elevated privileges to access the Amazon Bedrock service or other critical components.
  • Lacking multi-factor authentication (MFA) for AWS Identity and Access Management (IAM) users or roles with privileged access, increasing the risk of unauthorized access to AWS resources, including the Amazon Bedrock service, if credentials are compromised.

Mitigation strategies

To mitigate the risks associated with a lack of secure authentication and access controls, implement robust IAM controls, as well as continuous logging, monitoring, and threat detection mechanisms.

IAM controls:

  • Use industry-standard protocols like OAuth 2.0 or OpenID Connect, and integrate with AWS IAM Identity Center or other identity providers for centralized authentication and authorization for the Streamlit frontend interface and AWS API Gateway endpoints.
  • Implement fine-grained access controls using AWS IAM policies and resource-based policies to restrict access to only the necessary Amazon Bedrock resources, Lambda functions, and other components required for the chatbot application.
  • Enforce the use of MFA for all IAM users, roles, and service accounts with access to critical components like Amazon Bedrock, DynamoDB, or the Streamlit application.

Continuous logging and monitoring and threat detection:

  • See the Comprehensive logging and monitoring strategy section for guidance on implementing centralized logging and monitoring solutions to track and audit authentication events, access attempts, and potential unauthorized access or credential misuse across the chatbot application components and Amazon Bedrock service, as well as using CloudWatch, Lambda, and GuardDuty to detect and respond to anomalous behavior and potential threats.

Anti-pattern 2: Insufficient input sanitization and validation

Insufficient input validation and sanitization in a generative AI chatbot application can expose the system to various threats, including injection events, data tampering, adversarial events, and data poisoning events. These vulnerabilities can lead to unauthorized access, data manipulation, and compromised model outputs.

Injection events: If user prompts or inputs aren’t properly sanitized and validated, a threat actor can potentially inject malicious code, such as SQL code, leading to unauthorized access or manipulation of the DynamoDB chat history data. Additionally, if the chatbot application or components process user input without proper validation, a threat actor can potentially inject and run arbitrary code on the backend systems, compromising the entire application.

Data tampering: A threat actor can potentially modify user prompts or payloads in transit between the chatbot interface and Amazon Bedrock service, leading to unintended model responses or actions. Lack of data integrity checks can allow a threat actor to tamper with the context data exchanged between Amazon Bedrock and OpenSearch, potentially leading to incorrect or malicious search results influencing the LLM responses.

Data poisoning events: If the training data or context data used by the LLM or chatbot application isn’t properly validated and sanitized, bad actors can potentially introduce malicious or misleading data, leading to biased or compromised model outputs.

Anti-pattern examples

  • Failure to validate and sanitize user prompts before sending them to Amazon Bedrock, potentially leading to injection events or unintended data exposure.
  • Lack of input validation and sanitization for context data retrieved from OpenSearch, allowing malformed or malicious data to influence the LLM’s responses.
  • Insufficient sanitization of LLM-generated responses before displaying them to users, enabling potential code injection or rendering of harmful content.
  • Inadequate sanitization of user input in the Streamlit application or Lambda functions, failing to remove or escape special characters, code snippets, or potentially malicious patterns, enabling code injection events.
  • Insufficient validation and sanitization of training data or other data sources used by the LLM or chatbot application, allowing data poisoning events that can introduce malicious or misleading data, leading to biased or compromised model outputs.
  • Allowing unrestricted character sets, input lengths, or special characters in user prompts or data inputs, enabling adversaries to craft inputs that bypass input validation and sanitization mechanisms, potentially causing undesirable or malicious outputs.
  • Relying solely on deny lists for input validation, which can be quickly bypassed by adversaries, potentially leading to injection events, data tampering, or other exploit scenarios.

Mitigation strategies

To mitigate the risks associated with insufficient input validation and sanitization, implement robust input validation and sanitization mechanisms throughout the chatbot application and its components.

Input validation and sanitization:

  • Implement strict input validation rules for user prompts at the chatbot interface and Amazon Bedrock service boundaries, defining allowed character sets, maximum input lengths, and disallowing special characters or code snippets. Use Amazon Bedrock’s Guardrails feature, which allows defining denied topics and content filters to remove undesirable and harmful content from user interactions with your applications.
  • Use allow lists instead of deny lists for input validation to maintain a more robust and comprehensive approach.
  • Sanitize user input by removing or escaping special characters, code snippets, or potentially malicious patterns.

Data flow validation:

  • Validate and sanitize data flows between components, including:
    • User prompts sent to the FM and responses generated by the FM and returned to the chatbot interface.
    • Training data, context data, and other data sources used by the FM or chatbot application.

Protective controls:

  • Use AWS Web Application Firewall (WAF) for input validation and protection against common web exploits.
  • Use AWS Shield for protection against distributed denial of service (DDoS) events.
  • Use CloudTrail to monitor API calls to Amazon Bedrock, including InvokeModel requests.
  • See the Comprehensive logging and monitoring strategy section for guidance on implementing Lambda functions, Amazon EventBridge rules, and CloudWatch Logs to analyze CloudTrail logs, ingest application logs, user prompts, and responses, and integrate with incident response and SIEM solutions for detecting, investigating, and mitigating security incidents related to input validation and sanitization, including jailbreaking attempts and anomalous behavior.

Anti-pattern 3: Insecure communication channels

Insecure communication channels between chatbot application components can expose sensitive data to interception, tampering, and unauthorized access risks. Unsecured channels enable man-in-the-middle events where threat actors intercept, modify data in transit such as user prompts, responses, and context data, leading to data tampering, malicious payload injection, and unauthorized information access.

Anti-pattern examples

  • Failure to use AWS PrivateLink for secure service-to-service communication within the VPC, exposing communications between Amazon Bedrock and other AWS services to potential risks over the public internet, even when using HTTPS.
  • Absence of data integrity checks or mechanisms to detect and prevent data tampering during transmission between components.
  • Failure to regularly review and update communication channel configurations, protocols, and encryption mechanisms to address emerging threats and ensure compliance with security best practices.

Mitigation strategies

To mitigate the risks associated with insecure communication channels, implement secure communication mechanisms and enforce data integrity throughout the chatbot application’s components and their interactions. Proper encryption, authentication, and integrity checks should be employed to protect sensitive data in transit and help prevent unauthorized access, data tampering, and man-in-the-middle events.

Secure communication channels:

  • Use PrivateLink for secure service-to-service communication between Amazon Bedrock and other AWS services used in the chatbot application architecture. PrivateLink provides a private, isolated communication channel within the Amazon VPC, eliminating the need to traverse the public internet. This mitigates the risk of potential interception, tampering, or unauthorized access to sensitive data transmitted between services, even when using HTTPS.
  • Use AWS Certificate Manager (ACM) to manage and automate the deployment of SSL/TLS certificates used for secure communication between the chatbot frontend interface (the Streamlit application) and the API Gateway endpoint. ACM simplifies the provisioning, renewal, and deployment of SSL/TLS certificates, making sure that communication channels between the user-facing components and the backend API are securely encrypted using industry-standard protocols and up-to-date certificates.

Continuous logging and monitoring:

  • See the Comprehensive Logging and Monitoring Strategy section for guidance on implementing centralized logging and monitoring mechanisms to detect and respond to potential communication channel anomalies or security incidents, including monitoring communication channel metrics, API call patterns, request payloads, and response data, using AWS services like CloudWatch, CloudTrail, and AWS WAF.

Network segmentation and isolation controls

  • Implement network segmentation by deploying the Amazon ECS cluster within a dedicated VPC and subnets, isolating it from other components and restricting communication based on the principle of least privilege.
  • Create separate subnets within the VPC for the public-facing frontend tier and the backend application tier, further isolating the components.
  • Use AWS security groups and network access control lists (NACLs) to control inbound and outbound traffic at the instance and subnet levels, respectively, for the ECS cluster and the frontend instances.

Anti-pattern 4: Inadequate logging, auditing, and non-repudiation

Inadequate logging, auditing, and non-repudiation mechanisms in a generative AI chatbot application can lead to several risks, including a lack of accountability, challenges in forensic analysis, and compliance concerns. Without proper logging and auditing, it’s challenging to track user activities, diagnose issues, perform forensic analysis in case of security incidents, and demonstrate compliance with regulations or internal policies.

Anti-pattern examples

  • Lack of logging for data flows between components, such as user prompts sent to Amazon Bedrock, context data exchanged with OpenSearch, and responses from the LLM, hindering investigative efforts in case of security incidents or data breaches.
  • Insufficient logging of user activities within the chatbot application—such as sign in attempts, session duration, and actions performed—limiting the ability to track and attribute actions to specific users.
  • Absence of mechanisms to ensure the integrity and authenticity of logged data, allowing potential tampering or repudiation of logged events.
  • Failure to securely store and protect log data from unauthorized access or modification, compromising the reliability and confidentiality of log information.

Mitigation strategies

To mitigate the risks associated with inadequate logging, auditing, and non-repudiation, implement comprehensive logging and auditing mechanisms to capture critical events, user activities, and data flows across the chatbot application components. Additionally, measures must be taken to maintain the integrity and authenticity of log data, help prevent tampering or repudiation, and securely store and protect log information from unauthorized access.

Comprehensive logging and auditing:

  • See the Comprehensive logging and monitoring strategy section for detailed guidance on implementing logging mechanisms using CloudTrail, CloudWatch Logs, and OpenSearch Service, as well as using CloudTrail for logging and monitoring API calls, especially Amazon Bedrock API calls and other API activities within the AWS environment, using CloudWatch for monitoring Amazon Bedrock-specific metrics, and ensuring log data integrity and non-repudiation through the CloudTrail log file integrity validation feature and implementing S3 Object Lock and S3 Versioning for log data stored in Amazon S3.
  • Make sure that log data is securely stored and protected from unauthorized access by using AWS Key Management Service (AWS KMS) for encryption at rest and implementing restrictive IAM policies and resource-based policies to control access to log data.
  • Retain log data for an appropriate period based on compliance requirements, using CloudTrail log file integrity validation and CloudWatch Logs retention periods and data archiving capabilities.

User activity monitoring and tracking:

  • Use CloudTrail for logging and monitoring API calls, especially Amazon Bedrock API calls and other API activities within the AWS environment, such as API Gateway, Lambda, and DynamoDB. Additionally, use CloudWatch for monitoring metrics specific to Amazon Bedrock, including the number of model invocations, latency, and error metrics (client-side errors, server-side errors, and throttling).
  • Integrate with security information and event management (SIEM) solutions for centralized log management and real-time monitoring of security events.

Data integrity and non-repudiation:

  • Implement digital signatures or non-repudiation mechanisms to verify the integrity and authenticity of logged data, minimizing tampering or repudiation of logged events. Use the CloudTrail log file integrity validation feature, which uses industry-standard algorithms (SHA-256 for hashing and SHA-256 with RSA for digital signing) to provide non-repudiation and verify log data integrity. For log data stored in Amazon S3, enable S3 Object Lock and S3 Versioning to provide an immutable, write once, read many (WORM) data storage model, helping to prevent object deletions or modifications, and maintaining data integrity and non-repudiation. Additionally, implement S3 bucket policies and IAM policies to restrict access to log data stored in S3, further enhancing the security and non-repudiation of logged events.

Anti-pattern 5: Insecure data storage and access controls

Insecure data storage and access controls in a generative AI chatbot application can lead to significant risks, including information disclosure, data tampering, and unauthorized access. Storing sensitive data, such as chat history, in an unencrypted or insecure manner can result in information disclosure if the data store is compromised or accessed by unauthorized entities. Additionally, a lack of proper access controls can allow unauthorized parties to access, modify, or delete data, leading to data tampering or unauthorized access.

Anti-pattern examples

  • Storing chat history data in DynamoDB without encryption at rest using AWS KMS customer-managed keys (CMKs).
  • Lack of encryption at rest using CMKs from AWS KMS for data in OpenSearch, Amazon S3, or other components that handle sensitive data.
  • Overly permissive access controls or lack of fine-grained access control mechanisms for the DynamoDB chat history, OpenSearch, Amazon S3, or other data stores, increasing the risk of unauthorized access or data breaches.
  • Storing sensitive data in clear text, or using insecure encryption algorithms or key management practices.
  • Failure to regularly review and rotate encryption keys or update access control policies to address potential security vulnerabilities or changes in access requirements.

Mitigation strategies

To mitigate the risks associated with insecure data storage and access controls, implement robust encryption mechanisms, secure key management practices, and fine-grained access control policies. Encrypting sensitive data at rest and in transit, using customer-managed encryption keys from AWS KMS, and implementing least- privilege access controls based on IAM policies and resource-based policies can significantly enhance the security and protection of data within the chatbot application architecture.

Key management and encryption at rest:

  • Implement AWS KMS to manage and control access to CMKs for data encryption across components like DynamoDB, OpenSearch, and Amazon S3.
    • Use CMKs to configure DynamoDB to automatically encrypt chat history data at rest.
    • Configure OpenSearch and Amazon S3 to use encryption at rest with AWS KMS CMKs for data stored in these services.
    • CMKs provide enhanced security and control, allowing you to create, rotate, disable, and revoke encryption keys, enabling better key isolation and separation of duties.
    • CMKs enable you to enforce key policies, audit key usage, and adhere to regulatory requirements or organizational policies that mandate customer-managed encryption keys.
    • CMKs offer portability and independence from specific services, allowing you to migrate or integrate data across multiple services while maintaining control over the encryption keys.
    • AWS KMS provides a centralized and secure key management solution, simplifying the management and auditing of encryption keys across various components and services.
  • Implement secure key management practices, including:
    • Regular key rotation to maintain the security of your encrypted data.
    • Separation of duties to make sure that no single individual has complete control over key management operations.
    • Strict access controls for key management operations, using IAM policies and roles to enforce the principle of least privilege.

Fine-grained access controls:

  • Implement fine-grained access controls for the DynamoDB chat history data store, OpenSearch, Amazon S3, and other data stores using IAM policies and roles.
  • Implement fine-grained access controls and define least-privilege access policies for all resources handling sensitive data, such as the DynamoDB chat history data store, OpenSearch, Amazon S3, and other data stores or services. For example, use IAM policies and resource-based policies to restrict access to specific DynamoDB tables, OpenSearch domains, and S3 buckets, limiting access to only the necessary actions (for example, read, write, and list) based on the principle of least privilege. Extend this approach to all resources handling sensitive data within the chatbot application architecture, making sure that access is granted only to the minimum required resources and actions necessary for each component or user role.

Continuous improvement:

  • Regularly review and update encryption configurations, access control policies, and key management practices to address potential security vulnerabilities or changes in access requirements.

Anti-pattern 6: Failure to secure FM and generative AI components

Inadequate security measures for FMs and generative AI components in a chatbot application can lead to severe risks, including model tampering, unintended information disclosure, and denial of service. Threat actors can manipulate unsecured FMs and generative AI models to generate biased, harmful, or malicious responses, potentially causing significant harm or reputational damage.

Lack of proper access controls or input validation can result in unintended information disclosure, where sensitive data is inadvertently included in model responses. Additionally, insecure FM or generative AI components can be vulnerable to denial-of-service events, disrupting the availability of the chatbot application and impacting its functionality.

Anti-pattern examples

  • Insecure model fine tuning practices, such as using untrusted or compromised data sources, can lead to biased or malicious models.
  • Lack of continuous monitoring for FM and generative AI components, leaving them vulnerable to emerging threats or known vulnerabilities.
  • Lack of guardrails or safety measures to control and filter the outputs of FMs and generative AI components, potentially leading to the generation of harmful, biased, or undesirable content.
  • Inadequate access controls or input validation for prompts and context data sent to the FM components, increasing the risk of injection events or unintended information disclosure.
  • Failure to implement secure deployment practices for FM and generative AI components, including secure communication channels, encryption of model artifacts, and access controls.

Mitigation strategies

To mitigate the risks associated with inadequately secured foundational models (FMs) and generative AI components, implement secure integration mechanisms, robust model fine-tuning and deployment practices, continuous monitoring, and effective guardrails and safety measures. These mitigation strategies help prevent model tampering, unintended information disclosure, denial-of-service events, and the generation of harmful or undesirable content, while ensuring the security, reliability, and ethical alignment of the chatbot application’s generative AI capabilities.

Secure integration with LLMs and knowledge bases:

  • Implement secure communication channels (for example HTTPS or PrivateLink) between Amazon Bedrock, OpenSearch, and the FM components to help prevent unauthorized access or data tampering.
  • Implement strict input validation and sanitization for prompts and context data sent to the FM components to help prevent injection events or unintended information disclosure.
  • Implement access controls and least-privilege principles for the OpenSearch integration to limit the data accessible to the LLM components.

Secure model fine tuning, deployment, and monitoring:

  • Establish secure and auditable fine-tuning pipelines, using trusted and vetted data sources, to help prevent tampering or the introduction of biases.
  • Implement secure deployment practices for FM and generative AI components, including access controls, secure communication channels, and encryption of model artifacts.
  • Continuously monitor FM and generative AI components for security vulnerabilities, performance issues, and unintended behavior.
  • Implement rate-limiting, throttling, and load-balancing mechanisms to help prevent denial-of-service events on FM and generative AI components.
  • Regularly review and audit FM and generative AI components for compliance with security policies, industry best practices, and regulatory requirements.

Guardrails and safety measures

  • Implement guardrails, which are safety measures designed to reduce harmful outputs and align the behavior of FMs and generative AI components with human values.
  • Use keyword-based filtering, metric-based thresholds, human oversight, and customized guardrails tailored to the specific risks and cultural and ethical norms of each application domain.
  • Monitor the effectiveness of guardrails through performance benchmarking and adversarial testing.

Jailbreak robustness testing

  • Conduct jailbreak robustness testing by prompting the FMs and generative AI components with a diverse set of jailbreak attempts across different prohibited scenarios to identify weaknesses and improve model robustness.

Anti-pattern 7: Lack of responsible AI governance and ethics

While the previous anti-patterns focused on technical security aspects, it is equally important to address the ethical and responsible governance of generative AI systems. Without strong governance frameworks, ethical guidelines, and accountability measures, chatbot applications can result in unintended consequences, biased outcomes, and a lack of transparency and trust.

Anti-pattern examples

  • Lack of an established ethical AI governance framework, including principles, policies, and processes to guide the responsible development and deployment of the generative AI chatbot application.
  • Insufficient measures to ensure transparency, explainability, and interpretability of the LLM and generative AI components, making it difficult to understand and audit their decision-making processes.
  • Absence of mechanisms for stakeholder engagement, public consultation, and consideration of societal impacts, potentially leading to a lack of trust and acceptance of the chatbot application.
  • Failure to address potential biases, discrimination, or unfairness in the training data, models, or outputs of the generative AI system.
  • Inadequate processes for testing, validation, and ongoing monitoring of the chatbot application’s ethical behavior and alignment with organizational values and societal norms.

Mitigation strategies

To minimize a lack of responsible AI governance and ethics, establish a comprehensive ethical AI governance framework, promote transparency and interpretability, engage stakeholders and consider societal impacts, address potential biases and fairness issues, implement continuous improvement and monitoring processes, and use guardrails and safety measures. These mitigation strategies help to foster trust, accountability, and ethical alignment in the development and deployment of the generative AI chatbot application, mitigating the risks of unintended consequences, biased outcomes, and a lack of transparency.

Ethical AI governance framework:

  • Establish an ethical AI governance framework, including principles, policies, and processes to guide the responsible development and deployment of the generative AI chatbot application.
  • Define clear ethical guidelines and decision-making frameworks to address potential ethical dilemmas, biases, or unintended consequences.
  • Implement accountability measures, such as designated ethics boards, ethics officers, or external advisory committees, to oversee the ethical development and deployment of the chatbot application.

Transparency and interpretability:

  • Implement measures to promote transparency and interpretability of the LLM and generative AI components, allowing for auditing and understanding of their decision-making processes.
  • Provide clear and accessible information to stakeholders and users about the chatbot application’s capabilities, limitations, and potential biases or ethical considerations.

Stakeholder engagement and societal impact:

  • Establish mechanisms for stakeholder engagement, public consultation, and consideration of societal impacts, fostering trust and acceptance of the chatbot application.
  • Conduct impact assessments to identify and mitigate potential negative consequences or risks to individuals, communities, or society.

Bias and fairness:

  • Address potential biases, discrimination, or unfairness in the training data, models, or outputs of the generative AI system through rigorous testing, bias mitigation techniques, and ongoing monitoring.
  • Promote diverse and inclusive representation in the development, testing, and governance processes to reduce potential biases and blind spots.

Continuous improvement and monitoring:

  • Implement processes for ongoing testing, validation, and monitoring of the chatbot application’s behavior and alignment with organizational values and societal norms.
  • Regularly review and update the AI governance framework, policies, and processes to address emerging ethical challenges, societal expectations, and regulatory developments.

Guardrails and safety measures:

  • Implement guardrails, such as Guardrails for Amazon Bedrock, which are safety measures designed to reduce harmful outputs and align the behavior of LLMs and generative AI components with human values and responsible AI policies.
  • Use Guardrails for Amazon Bedrock to define denied topics and content filters to remove undesirable and harmful content from interactions between users and your applications.
    • Define denied topics using natural language descriptions to specify topics or subject areas that are undesirable in the context of your application.
    • Configure content filters to set thresholds for filtering harmful content across categories such as hate, insults, sexuality, and violence based on your use cases and responsible AI policies.
    • Use the personally identifiable information (PII) redaction feature to redact information such as names, email addresses, and phone numbers from LLM-generated responses or block user inputs that contain PII.
  • Integrate Guardrails for Amazon Bedrock with CloudWatch to monitor and analyze user inputs and LLM responses that violate defined policies, enabling proactive detection and response to potential issues.
  • Monitor the effectiveness of guardrails through performance benchmarking and adversarial testing, continuously refining and updating the guardrails based on real-world usage and emerging ethical considerations.

Jailbreak robustness testing:

  • Conduct jailbreak robustness testing by prompting the LLMs and generative AI components with a diverse set of jailbreak attempts across different prohibited scenarios to identify weaknesses and improve model robustness.

Anti-pattern 8: Lack of comprehensive testing and validation

Inadequate testing and validation processes for the LLM system and the generative AI chatbot application can lead to unidentified vulnerabilities, performance bottlenecks, and availability issues. Without comprehensive testing and validation, organizations might fail to detect potential security risks, functionality gaps, or scalability and performance limitations before deploying the application in a production environment.

Anti-pattern examples

  • Lack of functional testing to validate the correctness and completeness of the LLM’s responses and the chatbot application’s features and functionalities.
  • Insufficient performance testing to identify bottlenecks, resource constraints, or scalability limitations under various load conditions.
  • Absence of security testing, such as penetration testing, vulnerability scanning, and adversarial testing to uncover potential security vulnerabilities or model exploits.
  • Failure to incorporate automated testing and validation processes into a continuous integration and continuous deployment (CI/CD) pipeline, leading to manual and one-time testing efforts that might overlook critical issues.
  • Inadequate testing of the chatbot application’s integration with external services and components, such as Amazon Bedrock, OpenSearch, and DynamoDB, potentially leading to compatibility issues or data integrity problems.

Mitigation strategies

To address the lack of comprehensive testing and validation, implement a robust testing strategy encompassing functional, performance, security, and integration testing. Integrate automated testing into a CI/CD pipeline, conduct security testing like threat modeling and penetration testing, and use adversarial validation techniques. Continuously improve testing processes to verify the reliability, security, and scalability of the generative AI chatbot application.

Comprehensive testing strategy:

  • Establish a comprehensive testing strategy that includes functional testing, performance testing, load testing, security testing, and integration testing for the LLM system and the overall chatbot application.
  • Define clear testing requirements, test cases, and acceptance criteria based on the application’s functional and non-functional requirements, as well as security and compliance standards.

Automated testing and CI/CD integration:

  • Incorporate automated testing and validation processes into a CI/CD pipeline, enabling continuous monitoring and assessment of the LLM’s performance, security, and reliability throughout its lifecycle.
  • Use automated testing tools and frameworks to streamline the testing process, improve test coverage, and facilitate regression testing.

Security testing and adversarial validation:

  • Conduct threat modeling exercises early in the design process and as soon as the design is finalized for the chatbot application architecture to proactively identify potential security risks and vulnerabilities. Subsequently, conduct regular security testing—including penetration testing, vulnerability scanning, and adversarial testing—to uncover and validate identified security vulnerabilities or model exploits.
  • Implement adversarial validation techniques, such as prompting the LLM with carefully crafted inputs designed to expose weaknesses or vulnerabilities, to improve the model’s robustness and security.

Performance and load testing:

  • Perform comprehensive performance and load testing to identify potential bottlenecks, resource constraints, or scalability limitations under various load conditions.
  • Use tools and techniques for load generation, stress testing, and capacity planning to ensure the chatbot application can handle anticipated user traffic and workloads.

Integration testing:

  • Conduct thorough integration testing to validate the chatbot application’s integration with external services and components, such as Amazon Bedrock, OpenSearch, and DynamoDB, maintaining seamless communication and data integrity.

Continuous improvement:

  • Regularly review and update the testing and validation processes to address emerging threats, new vulnerabilities, or changes in application requirements.
  • Use testing insights and results to continuously improve the LLM system, the chatbot application, and the overall security posture.

Common mitigation strategies for all anti-patterns

  • Regularly review and update security measures, access controls, monitoring mechanisms, and guardrails for LLM and generative AI components to address emerging threats, vulnerabilities, and evolving responsible AI best practices.
  • Conduct regular security assessments, penetration testing, and code reviews to identify and remediate vulnerabilities or misconfigurations related to logging, auditing, and non-repudiation mechanisms.
  • Stay current with security best practices, guidance, and updates from AWS and industry organizations regarding logging, auditing, and non-repudiation for generative AI applications.

Secure and responsible architecture blueprint

After discussing the baseline chatbot application architecture and identifying critical security anti-patterns associated with generative AI applications built using Amazon Bedrock, we now present the secure and responsible architecture blueprint. This blueprint (Figure 2) incorporates the recommended mitigation strategies and security controls discussed throughout the anti-pattern analysis.

Figure 2: Secure and responsible generative AI chatbot architecture blueprint

Figure 2: Secure and responsible generative AI chatbot architecture blueprint

In this target state architecture, unauthenticated users interact with the chatbot application through the frontend interface (1), where it’s crucial to mitigate the anti-pattern of insufficient input validation and sanitization by implementing secure coding practices and input validation. The user inputs are then processed through AWS Shield, AWS WAF, and CloudFront (2), which provide DDoS protection, web application firewall capabilities, and a content delivery network, respectively. These services help mitigate insufficient input validation, web exploits, and lack of comprehensive testing by using AWS WAF for input validation and conducting regular security testing.

The user requests are then routed through API Gateway (3), which acts as the entry point for the chatbot application, facilitating API connections to the Streamlit frontend. To address anti-patterns related to authentication, insecure communication, and LLM security, it’s essential to implement secure authentication protocols, HTTPS/TLS, access controls, and input validation within API Gateway. Communication between the VPC resources and API Gateway is secured through VPC endpoints (4), using PrivateLink for secure private communication and attaching endpoint policies to control which AWS principals can access the API Gateway service (8), mitigating the insecure communication channels anti-pattern.

The Streamlit application (5) is hosted on Amazon ECS in a private subnet within the VPC. It hosts the frontend interface and must implement secure coding practices and input validation to mitigate insufficient input validation and sanitization. User inputs are then processed by Lambda (6), a serverless compute service hosted within the VPC, which connects to Amazon Bedrock, OpenSearch, and DynamoDB through VPC endpoints (7). These VPC endpoints have endpoint policies attached to control access, enabling secure private communication between the Lambda function and the services, mitigating the insecure communication channels anti-pattern. Within Lambda, strict input validation rules, allow-lists, and user input sanitization are implemented to address the input validation anti-pattern.

User requests from the chatbot application are sent to Amazon Bedrock (12), a generative AI solution that powers the LLM capabilities. To mitigate the failure to secure FM and generative AI components anti-pattern, secure communication channels, input validation, and sanitization for prompts and context data must be implemented when interacting with Amazon Bedrock.

Amazon Bedrock interacts with OpenSearch Service (9) using Amazon Bedrock knowledge bases to retrieve relevant context data for the user’s question. The knowledge base is created by ingesting public documents from Amazon S3 (10). To mitigate the anti-pattern of insecure data storage and access controls, implement encryption at rest using AWS KMS and fine-grained IAM policies and roles for access control within OpenSearch Service. Titan Embeddings (11) are the format of the vector embeddings, which represent the documents stored in Amazon S3. The vector format enables similarity calculation and retrieval of relevant information (12). To address the failure to secure FM and generative AI components anti-pattern, secure integration with Titan Embeddings and input data validation should be implemented.

The knowledge base data, user prompts, and context data are processed by Amazon Bedrock (13) with the Claude 3 LLM (14). To address the anti-patterns of failure to secure FM and generative AI components, as well as lack of responsible AI governance and ethics, secure communication channels, input validation, ethical AI governance frameworks, transparency and interpretability measures, stakeholder engagement, bias mitigation, and guardrails like Guardrails for Amazon Bedrock should be implemented.

The generated responses and recommendations are then stored and retrieved in Amazon DynamoDB (15) by the Lambda function. To mitigate insecure data storage and access, encrypting data at rest with AWS KMS (16) and implement fine-grained access controls through IAM policies and roles.

Comprehensive logging, auditing, and monitoring mechanisms are provided by CloudTrail (17), CloudWatch (18), and AWS Config (19) to address the inadequate logging, auditing, and non-repudiation anti-pattern. See the Comprehensive logging and monitoring strategy section for detailed guidance on implementing comprehensive logging, auditing, and monitoring mechanisms using CloudTrail, CloudWatch, CloudWatch Logs, and AWS Config to address the inadequate logging, auditing, and non-repudiation anti-pattern; including logging API calls made to Amazon Bedrock service, monitoring Amazon Bedrock-specific metrics, capturing and analyzing Bedrock invocation logs, and monitoring and auditing the configuration of resources related to the chatbot application and Amazon Bedrock service.

IAM (20) plays a crucial role in the overall architecture and in mitigating anti-patterns related to authentication and insecure data storage and access. IAM roles and permissions are critical in enforcing secure authentication mechanisms, least privilege access, multi-factor authentication, and robust credential management across the various components of the chatbot application. Additionally, service control policies (SCPs) can be configured to restrict access to specific models or knowledge bases within Amazon Bedrock, preventing unauthorized access or use of sensitive intellectual property.

Finally, GuardDuty (21), Amazon Inspector (22), Security Hub (23), and Security Lake (24) have been included as additional recommended services to further enhance the security posture of the chatbot application. GuardDuty (21) provides threat detection across the control and data planes, Amazon Inspector (22) enables vulnerability assessments and continuous monitoring of Amazon ECS and Lambda workloads. Security Hub (23) offers centralized security posture management and compliance checks, while Security Lake (24) acts as a centralized data lake for log analysis, integrated with CloudTrail and SecurityHub.

Conclusion

By identifying critical anti-patterns and providing comprehensive mitigation strategies, you now have a solid foundation for a secure and responsible deployment of generative AI technologies in enterprise environments.

The secure and responsible architecture blueprint presented in this post serves as a comprehensive guide for organizations that want to use the power of generative AI while ensuring robust security, data protection, and ethical governance. By incorporating industry-leading security controls—such as secure authentication mechanisms, encrypted data storage, fine-grained access controls, secure communication channels, input validation and sanitization, comprehensive logging and auditing, secure FM integration and monitoring, and responsible AI guardrails—this blueprint addresses the unique challenges and vulnerabilities associated with generative AI applications.

Moreover, the emphasis on comprehensive testing and validation processes, as well as the incorporation of ethical AI governance principles, makes sure that you can not only mitigate potential risks, but also promote transparency, explainability, and interpretability of the LLM components, while addressing potential biases and ensuring alignment with organizational values and societal norms.

By following the guidance outlined in this post and depicted in the architectural blueprint, you can proactively identify and mitigate potential risks, enhance the security posture of your generative AI-based chatbot solutions, protect sensitive data and intellectual property, maintain regulatory compliance, and responsibly deploy LLMs and generative AI technologies in your enterprise environments.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Magesh Dhanasekaran
Magesh Dhanasekaran

Magesh is a Security Architect at AWS. He has a proven track record providing information security consulting services to financial institutions and government agencies in Australia and the United States. Magesh uses his experience in cloud security architecture, digital transformation, and secure application development practices to provide security advice on AWS products and services. He currently holds multiple industry certifications.
Amy Tipple
Amy Tipple

Amy is a Senior Data Scientist with the Professional Services Data and Machine Learning team and has been with AWS for approximately four years. Amy has worked on several engagements involving generative AI and is an advocate for making sure that generative AI-related security is accessible and understandable for AWS users.

Create a customizable cross-company log lake for compliance, Part I: Business Background

Post Syndicated from Colin Carson original https://aws.amazon.com/blogs/big-data/create-a-customizable-cross-company-log-lake-for-compliance-part-i-business-background/

As described in a previous post, AWS Session Manager, a capability of AWS Systems Manager, can be used to manage access to Amazon Elastic Compute Cloud (Amazon EC2) instances by administrators who need elevated permissions for setup, troubleshooting, or emergency changes. While working for a large global organization with thousands of accounts, we were asked to answer a specific business question: “What did employees with privileged access do in Session Manager?”

This question had an initial answer: use logging and auditing capabilities of Session Manager and integration with other AWS services, including recording connections (StartSession API calls) with AWS CloudTrail, and recording commands (keystrokes) by streaming session data to Amazon CloudWatch Logs.

This was helpful, but only the beginning. We had more requirements and questions:

  • After session activity is logged to CloudWatch Logs, then what?
  • How can we provide useful data structures that minimize work to read out, delivering faster performance, using more data, with more convenience?
  • How do we support a variety of usage patterns, such as ongoing system-to-system bulk transfer, or an ad-hoc query by a human for a single session?
  • How should we share and implement governance?
  • Thinking bigger, what about the same question for a different service or across more than one use case? How do we add what other API activity happened before or after a connection—in other words, context?

We needed more comprehensive functionality, more customization, and more control than a single service or feature could offer. Our journey began where previous customer stories about using Session Manager for privileged access (similar to our situation), least privilege, and guardrails ended. We had to create something new that combined existing approaches and ideas:

  • Low-level primitives such as Amazon Simple Storage Service (Amazon S3).
  • Latest features and approaches of AWS, such as vertical and horizontal scaling in AWS Glue.
  • Our experience working with legal, audit, and compliance in large enterprise environments.
  • Customer feedback.

In this post, we introduce Log Lake, a do-it-yourself data lake based on logs from CloudWatch and AWS CloudTrail. We share our story in three parts:

  • Part 1: Business background – We share why we created Log Lake and AWS alternatives that might be faster or easier for you.
  • Part 2: Build – We describe the architecture and how to set it up using AWS CloudFormation templates.
  • Part 3: Add – We show you how to add invocation logs, model input, and model output from Amazon Bedrock to Log Lake.

Do you really want to do it yourself?

Before you build your own log lake, consider the latest, highest-level options already available in AWS–they can save you a lot of work. Whenever possible, choose AWS services and approaches that abstract away undifferentiated heavy lifting to AWS so you can spend time on adding new business value instead of managing overhead. Know the use cases services were designed for, so you have a sense of what they already can do today and where they’re going tomorrow.

If that doesn’t work, and you don’t see an option that delivers the customer experience you want, then you can mix and match primitives in AWS for more flexibility and freedom, as we did for Log Lake.

Session Manager activity logging

As we mentioned in our introduction, you can save logging data to AmazonS3, add a table on top, and query that table using Amazon Athena—this is what we recommend you consider first because it’s straightforward.

This would result in files with the sessionid in the name. If you want, you can process these files into a calendarday, sessionid, sessiondata format using an S3 event notification that invokes a function (and make sure to save it to a different bucket, in a different table, to avoid causing recursive loops). The function could derive the calendarday and sessionid from the S3 key metadata, and sessiondata would be the entire file contents.

Alternatively, you can sign to one log group in CloudWatch logs, have an Amazon Data Firehose subscription filter move that to S3 (this file would have additional metadata in the JSON content and more customization potential from filters). This was used in our situation, but it wasn’t enough by itself.

AWS CloudTrail Lake

CloudTrail Lake is for running queries on events over years of history and with near real-time latency and offers a deeper and more customizable view of events than CloudTrail Event history. CloudTrail Lake enables you to federate an event data store, which lets you view the metadata in the AWS Glue catalog and run Athena queries. For needs involving one organization and ongoing ingesting from a trail (or point-in-time import from Amazon S3, or both), you can consider CloudTrail Lake.

We considered CloudTrail Lake, as either a managed lake option or source for CloudTrail only, but ended up creating our own AWS Glue job instead. This was because of a combination of reasons, including full control over schema and jobs, ability to ingest data from an S3 bucket of our choosing as an ongoing source, fine-grained filtering on account, AWS Region, and eventName (eventName filtering wasn’t supported for management events ), and cost.

The cost of CloudTrail lake based on uncompressed data ingested (data size can be 10 times larger than in Amazon S3) was a factor for our use case. In one test, we found CloudTrail Lake to be 38 times faster to process the same workload as Log Lake, but Log Lake was 10–100 times less costly depending on filters, timing, and account activity. Our test workload was 15.9 GB file size in S3, 199 million events, and 400 thousand files, spread across over 150 accounts and 3 Regions. Filters Log Lake applied were eventname='StartSession', 'AssumeRole', 'AssumeRoleWithSAML', and five arbitrary allow listed accounts. These tests might be different from your use case, so you should do your own testing, gather your own data, and decide for yourself.

Other services

The products mentioned previously are the most relevant to the outcomes we were trying to accomplish, but you should consider security, identity, and compliance products on AWS, too. These products and features can be used either as an alternative to Log Lake or to add functionality.

As an example, Amazon Bedrock can add functionality in three ways:

  • To skip the search and query Log Lake for you
  • To summarize across logs
  • As a source for logs (similar to Session Manager as a source for CloudWatch logs)

Querying means you can have an AI agent query your AWS Glue catalog (such as the Log Lake catalog) for data-based results. Summarizing means you can use generative artificial intelligence (AI) to summarize your text logs from a knowledge base as part of retrieval augmented generation (RAG), to ask questions like “How many log files are exactly the same? Who changed IAM roles last night?” Considerations and limitations apply.

Adding Amazon Bedrock as a source means using invocation logging to collect requests and responses.

Because we wanted to store very large amounts of data frugally (compressed and columnar format, not text) and produce non-generative (data-based) results that can be used for legal compliance and security, we didn’t use Amazon Bedrock in Log Lake—but we will revisit this topic in Part 3 when we detail how to use the approach we used for Session Manager for Amazon Bedrock.

Business background

When we began talking with our business partners, sponsors, and other stakeholders, important questions, problems, opportunities, and requirements emerged.

Why we needed to do this

Legal, security, identity, and compliance authorities of the large enterprise we were working for had created a customer-specific control. To comply with the control objective, use of elevated privileges required a manager to manually review all available data (including any session manager activity) to confirm or deny if use of elevated privileges was justified. This was a compliance use case that, when solved, could be applied to more use cases such as auditing and reporting.

Note on terms:

  • Here, the customer in customer-specific control means a control that is solely the responsibility of a customer, not AWS, as described in the AWS Shared Responsibility Model.
  • In this article, we define auditing broadly as testing information technology (IT) controls to mitigate risk, by anyone, at any cadence (ongoing as part of day-to-day operations, or one time only). We don’t refer to auditing that is financial, only conducted by an independent third-party, or only at certain times. We use self-review and auditing interchangeably.
  • We also define reporting broadly as presenting data for a specific purpose in a specific format to evaluate business performance and facilitate data-driven decisions—such as answering “how many employees had sessions last week?”

The use case

Our first and most important use case was a manager who needed to review activity, such as from an after-hours on-call page the previous night. If the manager needed to have additional discussions with their employee or needed additional time to consider activity, they had up to a week (7 calendar days) before they needed to confirm or deny elevated privileges were needed, based on their team’s procedures. A manager needed to review an entire set of events that all share the same session, regardless of known keywords or specific strings, as part of all available data in AWS. This was the workflow:

  1. Employee uses homegrown application and standardized workflow to access Amazon EC2 with elevated privileges using Session Manager.
  2. API activity in CloudTrail and continuous logging to CloudWatch logs.
  3. The problem space – Data somehow gets procured, processed, and provided (this would become Log Lake later).
  4. Another homegrown system (different from step 1) presents session activity to managers and applies access controls (a manager should only review activity for their own employees, and not be able to peruse data outside their team). This data might be only one StartSession API call and no session details, or might be thousands of lines from cat file
  5. The manager reviews all available activity, makes an informed decision, and confirms or denies if use was justified.

This was an ongoing day-to-day operation, with a narrow scope. First, this meant only data available in AWS; if something couldn’t be captured by AWS, it was out of scope. If something was possible, it should be made available. Second, this meant only certain workflows; using Session Manager with elevated privileges for a specific, documented standard operating procedure.

Avoiding review

The simplest solution would be to block sessions on Amazon EC2 with elevated privileges, and fully automate build and deployment. This was possible for some but not all workloads, because some workloads required initial setup, troubleshooting, or emergency changes of Marketplace AMIs.

Is accurate logging and auditing possible?

We won’t extensively detail ways to bypass controls here, but there are important limitations and considerations we had to consider, and we recommend you do too.

First, logging isn’t available for sessionType Port, which includes SSH. This could be mitigated by ensuring employees can only use a custom application layer to start sessions without SSH. Blocking direct SSH access to EC2 instances using security group policies is another option.

Second, there are many ways to intentionally or accidentally hide or obfuscate activity in a session, making review of a specific command difficult or impossible. This was acceptable for our use case for multiple reasons:

  • A manager would always know if a session started and needed review from CloudTrail (our source signal). We joined to CloudWatch to meet our all available data requirement.
  • Continuous streaming to CloudWatch logs would log activity as it happened. Additionally, streaming to CloudWatch Logs supported interactive shell access, and our use case only used interactive shell access (sessionType Standard_Stream). Streaming isn’t supported for sessionType, InteractiveCommands, or NonInteractiveCommands.
  • The most important workflow to review involved an engineered application with one standard operating procedure (less variety than all the ways Session Manager could be used).
  • Most importantly, the manager was responsible for reviewing the reports and expected to apply their own judgement and interpret what happened. For example, a manager review could result in a follow up conversation with the employee that could improve business processes. A manager might ask their employee, “Can you help me understand why you ran this command? Do we need to update our runbook or automate something in deployment?”

To protect data against tampering, changes, or deletion, AWS provides tools and features such as AWS Identity and Access Management (IAM) policies and permissions and Amazon S3 Object Lock.

Security and compliance are a shared responsibility between AWS and the customer, and customers need to decide what AWS services and features to use for their use case. We recommend customers consider a comprehensive approach that considers overall system design and includes multiple layers of security controls (defense in depth). For more information, see the Security pillar of the AWS Well-Architected Framework.

Avoiding automation

Manual review can be a painful process, but we couldn’t automate review for two reasons: Legal requirements and to add friction to the feedback loop felt by a manager whenever an employee used elevated privileges, to discourage using elevated privileges.

Works with existing

We had to work with existing architecture, spanning thousands of accounts and multiple AWS Organizations. This meant sourcing data from buckets as an edge and point of ingress. Specifically, CloudTrail data was managed and consolidated outside of CloudTrail, across organizations and trails, into S3 buckets. CloudWatch data was also consolidated to S3 buckets, from Session Manager to CloudWatch Logs, with Amazon Data Firehose subscription filters on CloudWatch Logs pointing to S3. To avoid negative side effects on existing business processes, our business partners didn’t want to change settings in CloudTrail, CloudWatch, and Firehose. This meant Log Lake needed features and flexibility that enabled changes without impacting other workstreams using the same sources.

Event filtering is not a data lake

Before we were asked to help, there were attempts to do event filtering. One attempt tried to monitor session activity using Amazon EventBridge. This was limited to AWS API operations recorded by CloudTrail such as StartSession and didn’t include the information from inside the session, which was in CloudWatch Logs. Another attempt tried event filtering CloudWatch in the form of a subscription filter. Also, an attempt was made using EventBridge Event Bus with EventBridge rules, and storage in Amazon DynamoDB. These attempts didn’t deliver the expected results because of a combination of factors:

Size

Couldn’t accept large session log payloads because of the EventBridge PutEvents limit of 256 KB entry size. Saving large entries to Amazon S3 and using the object URL in the PutEvents entry would avoid this limitation in EventBridge, but wouldn’t pass the most important information the manager needed to review (the event’s sessionData element). This meant managing files and physical dependencies, and losing the metastore benefit of working with data as logical sets and objects.

Storage

Event filtering was a way to process data, not storage or a source of truth. We asked, how do we restore data lost in flight or destroyed after landing? If components are deleted or undergoing maintenance, can we still procure, process, and provide data—at all three layers independently? Without storage, no.

Data quality

No source of truth meant data quality checks weren’t possible.  We couldn’t answer questions like: “Did the last job process more than 90 percent of events from CloudTrail in DynamoDB?” or“What percentage are we missing from source to target?”

Anti-patterns

DynamoDB as long-term storage wasn’t the most appropriate data store for large analytical workloads, low I/O, and highly complex many-to-many joins.

Reading out

Deliveries were fast, but work (and time and cost) was needed after delivery. In other words, queries had to do extra work to transform raw data into the needed format at time of read, which had a significant, cumulative effect on performance and cost. Imagine users running a select * from table without any filters on years of data and paying for storage and compute of those queries.

Cost of ownership

Filtering by event contents (sessionData from CloudWatch) required knowledge of session behavior, which was business logic. This meant changes to business logic required changes to event filtering. Imagine being asked to change CloudWatch filters or EventBridge rules based on a business process change, and trying to remember where to make the change, or troubleshoot why expected events weren’t being passed. This meant a higher cost of ownership and slower cycle times at best, and inability to meet SLA and scale at worst.

Accidental coupling

Creates accidental coupling between downstream consumers and low-level events. Consumers who directly integrate against events might get different schemas at different times for the same events, or events they don’t need. There’s no way to manage data at a higher level than event, at the level of sets (like all events for one sessionid), or at the object level (a table designed for dependencies). In other words, there was no metastore layer that separated the schema from the files, like in a data lake.

More sources (data to load in)

There were other, less important use cases that we wanted to expand to later: inventory management and security.

For inventory management, such as identifying EC2 instances running a Systems Manager agent that’s missing a patch, finding IAM users with inline policies, or finding Redshift clusters with nodes that aren’t RA3. This data would come from AWS Config unless it isn’t a supported resource type. We cut inventory management from scope because AWS Config data could be added to an AWS Glue catalog later, and queried from Athena using an approach like the one described in How to query your AWS resource configuration states using AWS Config and Amazon Athena.

For security, Splunk and OpenSearch were already in use for serviceability and operational analysis, sourcing files from Amazon S3. Log Lake is a complementary approach sourcing from the same data, which adds metadata and simplified data structures at the cost of latency. For more information about having different tools analyze the same data, see Solving big data problems on AWS.

More use cases (reasons to read out)

We knew from the first meeting that this was a bigger opportunity than just building a dataset for sessions from Systems Manager for manual manager review. Once we had procured logs from CloudTrail and CloudWatch, set up Glue jobs to process logs into convenient tables, and were able to join across these tables, we could change filters and configuration settings to answer questions about additional services and use cases, too. Similar to how we process data for Session Manager, we could expand the filters on Log Lake’s Glue jobs, and add data for Amazon Bedrock model invocation logging. For other use cases, we could use Log Lake as a source for automation (rules-based or ML), deep forensic investigations, or string-match searches (such as IP addresses or user names).

Additional technical considerations

*How did we define session? We would always know if a session started from StartSession event in CloudTrail API activity. Regarding when a session ended, we did not use TerminateSession because this was not always present and we considered this domain-specific logic. Log Lake enabled downstream customers to decide how to interpret the data. For example, our most important workflow had a Systems Manager timeout of 15 minutes, and our SLA was 90 minutes. This meant managers knew a session with a start time more than 2 hours prior to the current time was already ended.

*CloudWatch data required additional processing compared to CloudTrail, because CloudWatch logs from Firehose were saved in gzip format without gz suffix and had multiple JSON documents in the same line that needed to be processed to be on separate lines. Firehose can transform and convert records, such as invoking a Lambda function to transform, convert JSON to ORC, and decompress data, but our business partners didn’t want to change existing settings.

How to get the data (a deep dive)

To support the dataset needed for a manager to review, we needed to identify API-specific metadata (time, event source, and event name), and then join it to session data. CloudTrail was necessary because it was the most authoritative source for AWS API activity, specifically StartSession and AssumeRole and AssumeRoleWithSAML events, and contained context that didn’t exist in CloudWatch Logs (such as the error code AccessDenied) which could be useful for compliance and investigation. CloudWatch was necessary because it contained the keystrokes in a session, in the CloudWatch log’s sessionData element. We needed to obtain the AWS source of record from CloudTrail, but we recommend you check with your authorities to confirm you really need to join to CloudTrail. We mention this in case you hear this question “why not derive some sort of earliest eventTime from CloudWatch logs, and skip joining to CloudTrail entirely? That would cut size and complexity by half.”

To join CloudTrail (eventTime, eventname, errorCode, errorMessage, and so on) with CloudWatch (sessionData), we had to do the following:

  1. Get the higher level API data from CloudTrail (time, event source, and event name), as the authoritative source for auditing Session Manager. To get this, we needed to look inside all CloudTrail logs and get only the rows with eventname=‘StartSession’ and eventsource=‘ssm.amazonaws.com’ (events from Systems Manager)—our business partners described this as looking for a needle in a haystack, because this could be only one session event across millions or billions of files. After we obtained this metadata, we needed to extract the sessionid to know what session to join it to, and we chose to extract sessionid from responseelements. Alternatively, we could use useridentity.sessioncontext.sourceidentity if a principal provided it while assuming a role (requires sts:SetSourceIdentity in the role trust policy).

Sample of a single record’s responseelements.sessionid value: "sessionid":"theuser-thefederation-0b7c1cc185ccf51a9"

The actual sessionid was the final element of the logstream: 0b7c1cc185ccf51a9.

  1. Next we needed to get all logs for a single session from CloudWatch. Similarly to CloudTrail, we needed to look inside all CloudWatch logs landing in Amazon S3 from Firehose to identify only the needles that contained "logGroup":"/aws/ssm/sessionlogs". Then, we could get sessionid from logstream or sessionId, and get session activity from the message.sessionData.

Sample of a single record’s logStream element: "sessionId": "theuser-thefederation-0b7c1cc185ccf51a9"

Note: Looking inside the log isn’t always necessary. We did it because we had to work with existing logs Firehose put to Amazon S3, which didn’t have the logstream (and sessionid) in the file name. For example, a file from Firehose might have a name like

cloudwatch-logs-otherlogs-3-2024-03-03-22-22-55-55239a3d-622e-40c0-9615-ad4f5d4381fa

If we were able to use the ability of Session Manager to send to S3 directly, the file name in S3 is the loggroup (theuser-thefederation-0b7c1cc185ccf51a9.dms)and could be used to derive sessionid without looking inside the file.

  1. Downstream of Log Lake, consumers could join on sessionid which was derived in the previous step.

What’s different about Log Lake

If you remember one thing about Log Lake, remember this: Log Lake is a data lake for compliance-related use cases, uses CloudTrail and CloudWatch as data sources, has separate tables for writing (original raw) and reading (read-optimized or readready), and gives you control over all components so you can customize it for yourself.

Here are some of the signature qualities of Log Lake:

Legal, identity, or compliance use cases

This includes deep dive forensic investigation, meaning use cases that are large volume, historical, and analytical. Because Log Lake uses Amazon S3, it can meet regulatory requirements that require write-once-read-many (WORM) storage.

AWS Well-Architected Framework

Log Lake applies real-world, time-tested design principles from the AWS Well-Architected Framework. This includes, but is not limited to:

Operational Excellence also meant knowing service quotas, performing workload testing, and defining and documenting runbook processes. If we hadn’t tried to break something to see where the limit is, then we considered it untested and inappropriate for production use. To test, we would determine the highest single day volume we’d seen in the past year, and then run that same volume in an hour to see if (and how) it would break.

High-Performance, Portable Partition Adding (AddAPart)

Log Lake adds partitions to tables using Lambda functions with SQS, a pattern we call AddAPart. This uses Amazon Simple Query Service (SQS) to decouple triggers (files landing in Amazon S3) from actions (associating that file with metastore partition). Think of this as having four F’s:

This means no AWS Glue crawlers, no alter table or msck repair table to add partitions in Athena, and can be reused across sources and buckets. The management of partitions in Log Lake makes using partition-related features available in AWS Glue, including AWS Glue partition indexes and workload partitioning and bounded execution.

File name filtering uses the same central controls for lower cost of ownership, faster changes, troubleshooting from one location, and emergency levers—this means that if you want to avoid log recursion happening from a specific account, or want to exclude a Region because of regulatory compliance, you can do it in one place, managed by your change control process, before you pay for processing in downstream jobs.

If you want to tell a team, “onboard your data source to our log lake, here are the steps you can use to self-serve,” you can use AddAPart to do that. We describe this in Part 2.

Readready Tables

In Log Lake, data structures offer differentiated value to users, and original raw data isn’t directly exposed to downstream users by default. For each source, Log Lake has a corresponding read-optimized readready table.

Instead of this:

from_cloudtrail_raw

from_cloudwatch_raw

Log Lake exposes only these to users:

from_cloudtrail_readready

from_cloudwatch_readready

In Part 2, we describe these tables in detail. Here are our answers to frequently asked questions about readready tables:

Q: Doesn’t this have an up-front cost to process raw into readready? Why not pass the work (and cost) to downstream users?

A: Yes, and for us the cost of processing partitions of raw into readready happened once and was fixed, and was offset by the variable costs of querying, which was from many company-wide callers (systemic and human), with high frequency, and large volume.

Q: How much better are readready tables in terms of performance, cost, and convenience? How do you achieve these gains? How do you measure “convenience”?

A: In most tests, readready tables are 5–10 times faster to query and more than 2 times smaller in Amazon S3. Log Lake applies more than one technique: omitting columns, partition design, AWS Glue partition indexes, data types (readready tables don’t allow any nested complex data types within a column, such as struct<struct>), columnar storage (ORC), and compression (ZLIB). We measure convenience as the amount of operations required to join on a sessionid; using Log Lake’s readready tables this is 0 (zero).

Q: Do raw and readready use the same files or buckets?

A: No, files and buckets are not shared. This decouples writes from reads, improves both write and read performance, and adds resiliency.

This question is important when designing for large sizes and scaling, because a single job or downstream read alone can span millions of files in Amazon S3. S3 scaling doesn’t happen immediately, so queries against raw or original data involving many tiny JSON files can cause S3 503 errors when it exceeds 5,500 GET/HEAD per second. More than one bucket helps avoid resource saturation. There is another option that we didn’t have when we created Log Lake: S3 Express One Zone. For reliability, we still recommend not putting all your files in one bucket. Also, don’t forget to filter your data.

Customization and control

You can customize and control all components (columns or schema, data types, compression, job logic, job schedule, and so on) because Log Lake is built using AWS primitives—such as Amazon SQS and Amazon S3—for the most comprehensive combination of features with the most freedom to customize. If you want to change something, you can.

From mono to many

Rather than one large, monolithic lake that is tightly coupled to other systems, Log Lake is just one node in a larger network of distributed data products across different data domains—this concept is data mesh. Just like the AWS APIs it is built on, Log Lake abstracts away heavy lifting and enables users to move faster, more efficiently, and not wait for centralized teams to make changes. Log Lake does not try to cover all use cases—instead, Log Lake’s data can be accessed and consumed by domain-specific teams, empowering business experts to self-serve.

When you need more flexibility and freedom

As builders, sometimes you want to dissect a customer experience, find problems, and figure out ways to make it better. That means going a layer down to mix and match primitives together to get more comprehensive features and more customization, flexibility, and freedom.

We built Log Lake for our long-term needs, but it would have been easier in the short-term to save Session Manager logs to Amazon S3 and query them with Athena. If you have considered what already exists in AWS, and you’re sure you need more comprehensive abilities or customization, read on to Part 2: Build, which explains Log Lake’s architecture and how you can set it up.

If you have feedback and questions, let us know in the comments section.

References


About the authors

Colin Carson is a Data Engineer at AWS ProServe. He has designed and built data infrastructure for multiple teams at Amazon, including Internal Audit, Risk & Compliance, HR Hiring Science, and Security.

Sean O’Sullivan is a Cloud Infrastructure Architect at AWS ProServe. He has over 8 years industry experience working with customers to drive digital transformation projects, helping architect, automate, and engineer solutions in AWS.

Federating access to Amazon DataZone with AWS IAM Identity Center and Okta

Post Syndicated from Carlos Gallegos original https://aws.amazon.com/blogs/big-data/federating-access-to-amazon-datazone-with-aws-iam-identity-center-and-okta/

Many customers rely today on Okta or other identity providers (IdPs) to federate access to their technology stack and tools. With federation, security teams can centralize user management in a single place, which helps simplify and brings agility to their day-to-day operations while keeping highest security standards.

To help develop a data-driven culture, everyone inside an organization can use Amazon DataZone. To realize the benefits of using Amazon DataZone for governing data and making it discoverable and available across different teams for collaboration, customers integrate it with their current technology stack. Handling access through their identity provider and preserving a familiar single sign-on (SSO) experience enables customers to extend the use of Amazon DataZone to users across teams in the organization without any friction while keeping centralized control.

Amazon DataZone is a fully managed data management service that makes it faster and simpler for customers to catalog, discover, share, and govern data stored across Amazon Web Services (AWS), on premises, and third-party sources. It also makes it simpler for data producers, analysts, and business users to access data throughout an organization so that they can discover, use, and collaborate to derive data-driven insights.

You can use AWS IAM Identity Center to securely create and manage identities for your organization’s workforce, or sync and use identities that are already set up and available in Okta or other identity provider, to keep centralized control of them. With IAM Identity Center you can also manage the SSO experience of your organization centrally, across your AWS accounts and applications.

This post guides you through the process of setting up Okta as an identity provider for signing in users to Amazon DataZone. The process uses IAM Identity Center and its native integration with Amazon DataZone to integrate with external identity providers. Note that, even though this post focuses on Okta, the presented pattern relies on the SAML 2.0 standard and so can be replicated with other identity providers.

Prerequisites

To build the solution presented in this post, you must have:

Process overview

Throughout this post you’ll follow these high-level steps:

  1. Establish a SAML connection between Okta and IAM Identity Center
  2. Set up automatic provisioning of users and groups in IAM Identity Center so that users and groups in the Okta domain are created in Identity Center.
  3. Assign users and groups to your AWS accounts in IAM Identity Center by assuming an AWS Identity and Access Management (IAM) role.
  4. Access the AWS Management Console and Amazon DataZone portal through Okta SSO.
  5. Manage Amazon DataZone specific permissions in the Amazon DataZone portal.

Setting up user federation with Okta and IAM Identity Center

This guide follows the steps in Configure SAML and SCIM with Okta and IAM Identity Center.

Before you get started, review the following items in your Okta setup:

  • Every Okta user must have a First name, Last name, Username and Display name value specified.
  • Each Okta user has only a single value per data attribute, such as email address or phone number. Users that have multiple values will fail to synchronize. If there are users that have multiple values in their attributes, remove the duplicate attributes before attempting to provision the user in IAM Identity Center. For example, only one phone number attribute can be synchronized. Because the default phone number attribute is work phone, use the work phone attribute to store the user’s phone number, even if the phone number for the user is a home phone or a mobile phone.
  • If you update a user’s address you must have streetAddress, city, state, zipCode and the countryCode value specified. If any of these values aren’t specified for the Okta user at the time of synchronization, the user (or changes to the user) won’t be provisioned.

Okta account

1) Establish a SAML connection between Okta and AWS IAM Identity Center

Now, let’s establish a SAML connection between Okta and AWS IAM Identity Center. First, you’ll create an application in Okta to establish the connection:

  1. Sign in to the Okta admin dashboard, expand Applications, then select Applications.
  2. On the Applications page, choose Browse App Catalog.
  3. In the search box, enter AWS IAM Identity Center, then select the app to add the IAM Identity Center app.

IAM identity center app in Okta

  1. Choose the Sign On tab.

IAM identity center app in Okta - sign on

  1. Under SAML Signing Certificates, select Actions, and then select View IdP Metadata. A new browser tab opens showing the document tree of an XML file. Select all of the XML from <md:EntityDescriptor> to </md:EntityDescriptor> and copy it to a text file.
  2. Save the text file as metadata.xml.

Identity provider metadata in Okta

Leave the Okta admin dashboard open, you will continue using it in the later steps.

Second, you’re going to set up Okta as an external identity provider in IAM Identity Center:

  1. Open the IAM Identity Center console as a user with administrative privileges.
  2. Choose Settings in the navigation pane.
  3. On the Settings page, choose Actions, and then select Change identity source.

Identity provider source in IAM identity center

  1. Under Choose identity source, select External identity provider, and then choose Next.

Identity provider source in IAM identity center

  1. Under Configure external identity provider, do the following:
    1. Under Service provider metadata, choose Download metadata file to download the IAM Identity Center metadata file and save it on your system. You will provide the Identity Center SAML metadata file to Okta later in this tutorial.
      1. Copy the following items to a text file for easy access (you’ll need these values later):
        • IAM Identity Center Assertion Consumer Service (ACS) URL
        • IAM Identity Center issuer URL
    2. Under Identity provider metadata, under IdP SAML metadata, choose Choose file and then select the metadata.xml file you created in the previous step.
    3. Choose Next.
  2. After you read the disclaimer and are ready to proceed, enter accept.
  3. Choose Change identity source.

Identity provider source in IAM identity center

Leave the AWS console open, because you will use it in the next procedure.

  1. Return to the Okta admin dashboard and choose the Sign On tab of the IAM Identity Center app, then choose Edit.
  2. Under Advanced Sign-on Settings enter the following:
    1. For ACS URL, enter the value you copied for IAM Identity Center Assertion Consumer Service (ACS) URL.
    2. For Issuer URL, enter the value you copied for IAM Identity Center issuer URL.
    3. For Application username format, select one of the options from the drop-down menu.
      Make sure the value you select is unique for each user. For this tutorial, select Okta username.
  3. Choose Save.

IAM identity center app in Okta - sign on

2) Set up automatic provisioning of users and groups in AWS IAM Identity Center

You are now able to set up automatic provisioning of users from Okta into IAM Identity Center. Leave the Okta admin dashboard open and return to the IAM Identity Center console for the next step.

  1. In the IAM Identity Center console, on the Settings page, locate the Automatic provisioning information box, and then choose Enable. This enables automatic provisioning in IAM Identity Center and displays the necessary System for Cross-domain Identity Management (SCIM) endpoint and access token information.

Automatic provisioning in IAM identity center

  1. In the Inbound automatic provisioning dialog box, copy each of the values for the following options:
    • SCIM endpoint
    • Access token

You will use these values to configure provisioning in Okta later.

  1. Choose Close.

Automatic provisioning in IAM identity center

  1. Return to the Okta admin dashboard and navigate to the IAM Identity Center app.
  2. On the AWS IAM Identity Center app page, choose the Provisioning tab, and then in the navigation pane, under Settings, choose Integration.
  3. Choose Edit, and then select the check box next to Enable API integration to enable provisioning.
  4. Configure Okta with the SCIM provisioning values from IAM Identity Center that you copied earlier:
    1. In the Base URL field, enter the SCIM endpoint Make sure that you remove the trailing forward slash at the end of the URL.
    2. In the API Token field, enter the Access token value.
  5. Choose Test API Credentials to verify the credentials entered are valid. The message AWS IAM Identity Center was verified successfully! displays.
  6. Choose Save. You are taken to the Settings area, with Integration selected.

API Integration in Okta

  1. Review the following setup before moving forward. In the Provisioning tab, in the navigation pane under Settings, choose To App. Check that all options are enabled. They should be enabled by default, but if not, enable them.

Application provision in Okta

3) Assign users and groups to your AWS accounts in AWS IAM Identity Center by assuming an AWS IAM role

By default, no groups nor users are assigned to your Okta IAM Identity Center app. Complete the following steps to synchronize users with IAM Identity Center.

  1. In the Okta IAM Identity Center app page, choose the Assignments tab. You can assign both people and groups to the IAM Identity Center app.
    1. To assign people:
      1. In the Assignments page, choose Assign, and then choose Assign to people.
      2. Select the Okta users that you want to have access to the IAM Identity Center app. Choose Assign, choose Save and Go Back, and then choose Done.
        This starts the process of provisioning the individual users into IAM Identity Center.

      Users assignment in Okta

    1. To assign groups:
      1. Choose the Push Groups tab. You can create rules to automatically provision Okta groups into IAM Identity Center.

      Groups assignment in Okta

      1. Choose the Push Groups drop-down list and select Find groups by rule.
      2. In the By rule section, set a rule name and a condition. For this post we’re using AWS SSO Rule as rule name and starts with awssso as a group name condition. This condition can be different depending on the name of the group you want to sync.
      3. Choose Create Rule

      Okta SSO group rule

      1. (Optional) To create a new group choose Directory in the navigation pane, and then choose Groups.

      Group creation in Okta

      1. Choose Add group and enter a name, and then choose Save.

      Group creation in Okta

      1. After you have created the group, you can assign people to it. Select the group name to manage the group’s users.

      Group user assign in Okta

      1. Choose Assign people and select the users that you want to assign to the group.

      Group user assign in Okta

      1. You will see the users that are assigned to the group.

      Group user assign in Okta

      1. Going back to Applications in the navigation pane, select the AWS IAM Identity Center app and choose the Push Groups tab. You should have the groups that match the rule synchronized between Okta and IAM Identity Center. The group status should be set to Active after the group and its members are updated in Identity Center.

      Active groups in Okta

  1. Return to the IAM Identity Center console. In the navigation pane, choose Users. You should see the user list that was updated by Okta.

Active users in IAM identity center

  1. In the left navigation, select Groups, you should see the group list that was updated by Okta.

Active groups in IAM identity center

Congratulations! You have successfully set up a SAML connection between Okta and AWS and have verified that automatic provisioning is working.

OPTIONAL: If you need to provide Amazon DataZone console access to the Okta users and groups, you can manage these permissions through the IAM Identity Center console.

  1. In the IAM Identity Center navigation pane, under Multi-account permissions, choose AWS accounts.
  2. On the AWS accounts page, the Organizational structure displays your organizational root with your accounts underneath it in the hierarchy. Select the checkbox for your management account, then choose Assign users or groups.

IAM Roles in IAM identity center

  1. The Assign users and groups workflow displays. It consists of three steps:
    1. For Step 1: Select users and groups choose the user that will be performing the administrator job function. Then choose Next.
    2. For Step 2: Select permission sets choose Create permission set to open a new tab that steps you through the three sub-steps involved in creating a permission set.
      1. For Step 1: Select permission set type complete the following:
        • In Permission set type, choose Predefined permission set.
        • In Policy for predefined permission set, choose AdministratorAccess.
      2. Choose Next.
      3. For Step 2: Specify permission set details, keep the default settings, and choose Next.
        The default settings create a permission set named AdministratorAccess with session duration set to one hour. You can also specify reduced permissions with a custom policy just to allow Amazon DataZone console access.
      4. For Step 3: Review and create, verify that the Permission set type uses the AWS managed policy AdministratorAccess or your custom policy. Choose Create. On the Permission sets page, a notification appears informing you that the permission set was created. You can close this tab in your web browser now.
  2. On the Assign users and groups browser tab, you are still on Step 2: Select permission sets from which you started the create permission set workflow.
  3. In the Permissions sets area, Refresh. The AdministratorAccess permission or your custom policy set you created appears in the list. Select the checkbox for that permission set, and then choose Next.

IAM Roles in IAM identity center

    1. For Step 3: Review and submit review the selected user and permission set, then choose Submit.
      The page updates with a message that your AWS account is being configured. Wait until the process completes.
    2. You are returned to the AWS accounts page. A notification message informs you that your AWS account has been re-provisioned, and the updated permission set is applied. When a user signs in, they will have the option of choosing the AdministratorAccess role or a custom policy role.

4) Access the AWS console and Amazon DataZone portal through Okta SSO

Now, you can test your user access into the console and Amazon DataZone portal using the Okta external identity application.

  1. Sign in to the Okta dashboard using a test user account.
  2. Under My Apps, select the AWS IAM Identity Center icon.

IAM identity center access in Okta

  1. Complete the authentication process using your Okta credentials.

IAM identity center access in Okta

4.1) For administrative users

  1. You’re signed in to the portal and can see the AWS account icon. Expand that icon to see the list of AWS accounts that the user can access. In this tutorial, you worked with a single account, so expanding the icon only shows one account.
  2. Select the account to display the permission sets available to the user. In this tutorial you created the AdministratorAccess permission set.
  3. Next to the permission set are links for the type of access available for that permission set. When you created the permission set, you specified both management console and programmatic access be enabled, so those two options are present. Select Management console to open the console.

AWS Management console

  1. The user is signed in to the console. Using the search bar, look for Amazon DataZone service and open it.
  2. Open the Amazon DataZone console and make sure you have enabled SSO users through IAM Identity Center. In case you haven’t, you can follow the steps in Enable IAM Identity Center for Amazon DataZone.

Note: In this post, we followed the default IAM Identity Center for Amazon DataZone configuration, which has implicit user assignment mode enabled. With this option, any user added to your Identity Center directory can access your Amazon DataZone domain automatically. If you opt for using explicit user assignment instead, remember that you need to manually add users to your Amazon DataZone domain in the Amazon DataZone console for them to have access.
To learn more about how to manage user access to an Amazon DataZone domain, see Manage users in the Amazon DataZone console.

  1. Choose the Open data portal to access the Amazon DataZone Portal.

DataZone console

4.2) For all other users

  1. Choose the Applications tab in the AWS access portal window and choose the Amazon DataZone data portal application link.

DataZone application

  1. In the Amazon DataZone data portal, choose SIGN IN WITH SSO to continue

DataZone portal

Congratulations! Now you’re signed in to the Amazon DataZone data portal using your user that’s managed by Okta.

DataZone portal

5) Manage Amazon DataZone specific permissions in the Amazon DataZone portal

After you have access to the Amazon DataZone portal, you can work with projects, the data assets within, environments, and other constructs that are specific to Amazon DataZone. A project is the overarching construct that brings together people, data, and analytics tools. A project has two roles: owner and contributor. Next, you’ll learn how a user can be made an owner or contributor of existing projects.

These steps must be completed by the existing project owner in the Amazon DataZone portal:

  1. Open the Amazon DataZone portal, select the project in the drop-down list on the left top of the portal and choose the project you own

DataZone project

  1. In the project window, choose the Members tab to see the current users in the project and add a new one.

DataZone project members

  1. Choose Add Members to add a new user. Make sure the User type is SSO User to add an Okta user. Look for the Okta user in the name drop-down list, select it, and select a project role for it. Finally, choose Add Members to add the user.

DataZone project members

  1. The Okta user has been granted the selected project role and can interact with the project, assets, and tools.

DataZone project members

  1. You can also grant permissions to SSO Groups. Choose Add members, then select SSO group in the drop-down list, next select the Group name, set the assigned project role, and choose Add Members.

DataZone project members

  1. The Okta group has been granted the project role and can interact with the project, assets, and tools.

DataZone project members

You can also manage SSO user and group access to the Amazon DataZone data portal from the console. See Manage users in the Amazon DataZone console for additional details.

Clean up

To ensure a seamless experience and avoid any future charges, we kindly request that you follow these steps:

By following these steps, you can effectively clean up the resources utilized in this blog post and prevent any unnecessary charges from accruing.

Summary

In this post, you followed a step-by-step guide to set up and use Okta to federate access to Amazon DataZone with AWS IAM Identity Center. You also learned how to group users and manage their permission in Amazon DataZone. As a final thought, now that you’re familiar with the elements involved in the integration of an external identity provider such as Okta to federate access to Amazon DataZone, you’re ready to try it with other identity providers.

To learn more about, see Managing Amazon DataZone domains and user access.


About the Authors

Carlos Gallegos is a Senior Analytics Specialist Solutions Architect at AWS. Based in Austin, TX, US. He’s an experienced and motivated professional with a proven track record of delivering results worldwide. He specializes in architecture, design, migrations, and modernization strategies for complex data and analytics solutions, both on-premises and on the AWS Cloud. Carlos helps customers accelerate their data journey by providing expertise in these areas. Connect with him on LinkedIn.

Jose Romero is a Senior Solutions Architect for Startups at AWS. Based in Austin, TX, US. He’s passionate about helping customers architect modern platforms at scale for data, AI, and ML. As a former senior architect in AWS Professional Services, he enjoys building and sharing solutions for common complex problems so that customers can accelerate their cloud journey and adopt best practices. Connect with him on LinkedIn.

Arun Pradeep Selvaraj is a Senior Solutions Architect at AWS. Arun is passionate about working with his customers and stakeholders on digital transformations and innovation in the cloud while continuing to learn, build, and reinvent. He is creative, fast-paced, deeply customer-obsessed and uses the working backwards process to build modern architectures to help customers solve their unique challenges. Connect with him on LinkedIn.

How to deploy an Amazon OpenSearch cluster to ingest logs from Amazon Security Lake

Post Syndicated from Kevin Low original https://aws.amazon.com/blogs/security/how-to-deploy-an-amazon-opensearch-cluster-to-ingest-logs-from-amazon-security-lake/

January 30, 2025: This post was republished to make the instructions clearer and compatible with OCSF 1.1.


Customers often require multiple log sources across their AWS environment to empower their teams to respond and investigate security events. In part one of this two-part blog post, I show you how you can use Amazon OpenSearch Service to ingest logs collected by Amazon Security Lake to facilitate near real-time monitoring.

Many customers use Security Lake to automatically centralize security data from Amazon Web Services (AWS) environments, software as a service (SaaS) providers, on-premises workloads, and cloud sources into a purpose-built data lake in their AWS environment. OpenSearch Service is a managed service that customers can use to deploy, operate, and scale OpenSearch clusters in the AWS Cloud. It natively integrates with Security Lake to enable customers to perform interactive log analytics and searches across large datasets, create enterprise visualization and dashboards, and perform analysis across disparate applications and logs. With Amazon OpenSearch Security Analytics, customers can also gain visibility into the security posture of their organization’s infrastructure, monitor for anomalous activity, detect potential security threats in near real time, and initiate alerts to pre-configured destinations.

Without using Amazon OpenSearch Service, customers would need to build, deploy and manage infrastructure for an analytics solution, such as an ELK stack.

Prerequisites

Security Lake should already be deployed. For details on how to deploy Security Lake, see Getting started with Amazon Security Lake. You will need AWS Identity and Access Management (IAM) permissions to manage Security Lake, OpenSearch Service, Amazon Cognito, AWS Secrets Manager, and Amazon Elastic Compute Cloud (Amazon EC2), and to create IAM roles to follow along with this post. The solution can be deployed in any AWS Region that has at least 3 Availability Zones, supports Security Lake, OpenSearch, and OpenSearch Ingestion.

Solution overview

The architecture diagram in Figure 1 shows the completed architecture of the solution.

  1. The OpenSearch Service cluster is deployed within a virtual private cloud (VPC) across three Availability Zones for high availability.
  2. The OpenSearch Service cluster ingests logs from Security Lake using an OpenSearch Ingestion pipeline.
  3. The cluster is accessed by end users through a public-facing proxy hosted on an Amazon EC2 instance.
    1. To reduce costs, the template doesn’t deploy a dead letter queue (DLQ) for the OpenSearch Ingestion pipeline. You can add one later if you want.
    2. Instead of a public facing proxy, you can deploy a VPN to access your cluster.
  4. Authentication to the cluster is managed with Amazon Cognito.

Figure 1: Solution architecture

Figure 1: Solution architecture

Planning the deployment

This section will help you plan your OpenSearch service deployment, including what nodes you should choose, the amount of storage to allocate, and where to deploy the cluster.

Deciding instances for the OpenSearch Service master and data nodes

First, determine what instance type to use for the master and data nodes. If your workload generates less than 100 GB of Security Lake logs per day, we recommend using three m6g.large.search master nodes and three r6g.large.search data nodes. You can start small and scale up or scale out later. For more information about deciding the size and number of instances, see Get started with Amazon OpenSearch Service. Note the instance types that you have selected on a text editor because you will use this as an input for the AWS CloudFormation template that you will deploy later.

Configuring storage

To optimize your storage costs, you need to plan your data strategy. In this architecture, Security Lake is used for long-term log storage. Because Security Lake uses Amazon Simple Storage Service (Amazon S3), you can optimize long-term storage costs. You can configure OpenSearch Service to ingest priority logs based on the recent data that you can use for near-real time detection and alerting. Your team can query logs in Security Lake using its Zero-ETL integration with OpenSearch Service to analyze older logs.

Therefore, Security Lake should serve as your primary long-term log storage, with OpenSearch Service storing only the most recent logs.

The number of days of logs in OpenSearch Service will depend on how many days’ worth of data you need to investigate at a given time. I recommend storing 15 days of data in OpenSearch Service. This allows you to react to and investigate the most immediate security events while optimizing storage costs for older logs.

The next step is to determine the volume of logs generated by Security Lake.

  1. Sign in to the Security Lake delegated administrator account.
  2. Go to the AWS Management Console for Security Lake. Choose Usage in the navigation pane.
  3. On the Usage screen, select Last 30 days as the range of usage.
  4. Add the total Actual usage for the last 30 days for the data sources that you intend to send to OpenSearch. If you have used Security Lake for less than 30 days, you can use the Total predicted usage per month. Divide this figure by 30 to get the daily data volume.

Figure 2: Select range of usage

Figure 2: Select range of usage

To determine the total storage needed, multiply the data generated by Security Lake per day by the retention period you chose, then by 1.1 to account for the indexes, then multiply that number by 1.15 for overhead storage. For more information about calculating storage, see Get started with Amazon OpenSearch Service.

To determine the amount of Amazon Elastic Block Store (Amazon EBS) storage that you need per node, take the total amount of storage and divide it by the number of nodes that you have. Round that number up to the nearest whole number. You can increase the amount of storage after deployment when you have a better understanding of your workload. Make a note of this number in a text editor because you’ll use it as an input in the CloudFormation template later.

Example 1: 10 GB of Security Lake logs generated per day, stored for 30 days in OpenSearch Service in three nodes

  • 10 GB of Security Lake logs stored for 30 days = 10 GB * 30 = 300 GB
  • Account for additional space for indexes and overhead space = 300 GB * 1.1 * 1.15 = 379.5 GB
  • Divide the storage required across three nodes, rounded up = 379.5/3 ≈ 127 GB per node
  • You would need 127 GB per node in OpenSearch Service

Example 2: 200 GB of Security Lake logs generated per day, stored for 15 days in OpenSearch Service across six nodes

  • 200 GB of Security Lake logs stored for 15 days = 200 GB * 15 = 3000 GB
  • Account for additional space for indexes and overhead space = 3000 GB * 1.1 * 1.15 = 3795 GB
  • Divide the storage required across three nodes, rounded up = 3795/6 ≈ 633 GB per node
  • You would need 633 GB per node in OpenSearch Service

Where to deploy the cluster?

If you have an AWS Control Tower deployment or have a deployment modelled after the AWS Security Reference Architecture (AWS SRA), Security Lake should be deployed in the Log Archive account. Because security best practices recommend that the Log Archive account should not be frequently accessed, the OpenSearch Service cluster should be deployed into your Audit account or Security Tooling account.

You need to deploy your Security Lake subscriber in the same Region as your Security Lake roll-up Region. If you have more than one roll-up Region, choose the Region that collects logs from the Regions you want to monitor.

Your cluster needs to be deployed in the same Region as your Security Lake subscriber be able to access data.

Setting up the Security Lake subscriber

Before deploying the solution, create a Security Lake subscriber in your Security Lake roll-up Region so that OpenSearch Service can access data from Amazon Security Lake.

  1. Access the Security Lake console in your Log Archive account.
  2. Choose Subscribers in the navigation pane.
  3. Choose Create subscriber.
  4. On the Create subscriber page, enter a name, such as OpenSearch-subscriber.
  5. Under Data Access, select Under S3 notification type, select SQS queue.
  6. Under Subscriber credentials, enter the AWS account ID for the account you plan to deploy the OpenSearch cluster to, which should be your Security Tooling
  7. Enter OpenSearchIngestion-<AWS account ID> under External ID.

    Figure 3: Configuring the Security Lake subscriber

    Figure 3: Configuring the Security Lake subscriber

  8. Leave All log and event sources selected and choose Create.

After the subscriber has been created, you will need to collect information to facilitate the deployment.

To gather necessary information:

  1. Select the subscriber that you just created.
  2. Derive the S3 bucket name from the S3 bucket ARN and store it in a text editor. The Amazon Resource Name (ARN) is formatted as arn:aws:s3:::<bucket name>. The bucket name should look like aws-security-data-lake-<region>-xxxxx.

    Figure 4: Derive the S3 bucket name from the Subscriber details page

    Figure 4: Derive the S3 bucket name from the Subscriber details page

  3. Go to the Amazon Simple Queue Service (Amazon SQS) console and select the SQS queue created as part of the Security Lake subscriber. It should look like AmazonSecurityLake-xxxxxxxxx-Main-Queue. Note the queue’s ARN and URL in your text editor.

    Figure 5: Relevant details from the SQS queue

    Figure 5: Relevant details from the SQS queue

Deploy the solution

To deploy the solution in your Security Tooling account, use a CloudFormation template. This template deploys the OpenSearch Service cluster, OpenSearch Ingestion pipeline, and an AWS Lambda function to initialize the cluster.

To deploy the OpenSearch cluster:

  1. To deploy the CloudFormation template that builds the OpenSearch service cluster, select the Launch Stack button.

    Select this image to open a link that starts building the CloudFormation stack

  2. In the CloudFormation console, make sure that you are in the correct AWS account. You should be in your Security Tooling account. Also make sure that you have selected the same Region as your Security Lake subscriber.
  3. Enter a name for your stack. A name like os-stack-<day>-<month> can help you keep track of deployments.
  4. Enter the instance types and Amazon EBS volume size that you noted earlier.
  5. Enter the IP address range that you want to allow to access the proxy’s security group. You should limit this to your corporate IP range. You can set it as 0.0.0/0 if you want to expose it to the public internet.
  6. Fill in the details of the Security Lake bucket and the subscriber Amazon SQS queue ARN, URL, and Region.

    Figure 6: Add stack parameters

    Figure 6: Add stack parameters

  7. Check the acknowledgements in the Capabilities section.
  8. Choose Create stack to begin deploying the resources.
  9. It will take 20–30 minutes to deploy the multiple nested templates. Wait for the main stack (not the nested ones) to achieve the CREATE_COMPLETE status before proceeding to the next step.

    Note: If you encounter failures while deployment, you can download the CloudFormation file here and select Preserve successfully provisioned resources under Stack failure options while deploying. This will allow you to troubleshoot the stack deployment.

  10. Go to the Outputs pane of the main CloudFormation stack. Save the DashboardsProxyURL, OpenSearchInitRoleARN, and PipelineRole values in a text editor to refer to later.

    Figure 7: The stacks in the CREATE_COMPLETE state with the outputs panel shown

    Figure 7: The stacks in the CREATE_COMPLETE state with the outputs panel shown

  11. Open the DashboardsProxyURL value in a new tab.

    Note: Because the proxy relies on a self-signed certificate, you will get an insecure certificate warning. You can safely ignore this warning and proceed. For a production workload, you should issue a trusted private certificate from your internal public key infrastructure or use AWS Private Certificate Authority.

  12. You will be presented with the Amazon Cognito sign-in page. Use administrator as the username.
  13. Access Secrets Manager to find the password. Select the secret that was created as part of the stack.

    Figure 9: Retrieve the secret value

    Figure 8: The Cognito password in Secrets Manager

  14. Choose Retrieve secret value to get the password.

    Figure 9: Retrieve the secret value

    Figure 9: Retrieve the secret value

  15. After signing in, you will be prompted to change your password and will be redirected to the OpenSearch dashboard.
  16. If you see a pop-up that states Start by adding your own data, select Explore on my own. On the next page, Introducing new OpenSearch Dashboards look & feel, choose Dismiss.
  17. If you see a pop-up that states Select your tenant, select Global, and then choose Confirm.

    Figure 10: Select and confirm your tenant

    Figure 10: Select and confirm your tenant

To initialize the OpenSearch cluster:

  1. Choose the menu icon (three stacked horizontal lines) on the top left and select Security under the Management section.

    Figure 11: Navigating to the Security page in the OpenSearch console

    Figure 11: Navigating to the Security page in the OpenSearch console

  2. Select Roles. On the Roles page, search for the all_access role and select it.
  3. Select Mapped users, and then select Manage mapping.
  4. On the Map user screen, choose Add another backend role. Paste the value for the OpenSearchInitRoleARN from the list of CloudFormation outputs. Choose Map.

    Figure 12: Mapping the role on the Security page in the OpenSearch console

    Figure 12: Mapping the role on the Security page in the OpenSearch console

  5. Leave this tab open and return to the AWS Management console. Go to the AWS Lambda console and select the function named xxxxxx-OS_INIT.
  6. In the function screen, choose Test, and then Create new test event.

    Figure 13: Creating the test event in the Lambda console

    Figure 13: Creating the test event in the Lambda console

  7. Choose Invoke. The function should run for about 30 seconds. The execution results should show the component templates that have been created. This Lambda function creates the component and index templates to ingest Open Cybersecurity Framework (OCSF) formatted data, a set of indices and aliases that correspond with the OCSF classes generated by Security Lake, and a rollover policy that will rollover the index daily or if it becomes larger than 40 GB.

    Figure 14: Invoking the Lambda function in the Lambda console

    Figure 14: Invoking the Lambda function in the Lambda console

To set up the pipeline

  1. Return to the Map user page on the OpenSearch console.
  2. Choose Add another backend role. Paste the value of the PipelineRole from the CloudFormation template output. Choose This will allow the OpenSearch Ingestion to write to the cluster.

    Figure 15: Mapping the OpenSearch Ingestion role

    Figure 15: Mapping the OpenSearch Ingestion role

  3. Access the Amazon S3 console in the Log Archive account where Security Lake is hosted.
  4. Select the Security Lake bucket in your roll-up Region. It should look like aws-security-data-lake-region-xxxxxxxxxx.
  5. Choose Permissions, then Edit under Bucket policy.
  6. Add this policy to the end of the existing bucket policy. Replace the Principal with the ARN of the PipelineRole and the name of your Security Lake bucket in the Resource section.
    {
                "Sid": "Cross Account Permissions",
                "Effect": "Allow",
                "Principal": {
                    "AWS": "<Pipeline role ARN>"
                },
                "Action": "s3:*",
                "Resource": [
                    "arn:aws:s3:::<Security Lake bucket name>/*",
                    "arn:aws:s3:::<Security Lake bucket name>"
                ]
            }

    Figure 16: The modified S3 bucket access policy

    Figure 16: The modified S3 bucket access policy

  7. Choose Save changes.

To upload the index patterns and dashboards

  1. Download the Security-lake-objects.ndjson file by right-clicking on this link and selecting Save link as.
  2. Access the Dashboards Management page through the navigation menu.
  3. Choose Saved objects in the navigation pane.
  4. On the Saved Objects page, choose Import on the right side of the screen.

    Figure 17: Import saved objects

    Figure 17: Import saved objects

  5. Choose Import and select the Security-lake-objects.ndjson file that you downloaded previously.
  6. Leave Create new objects with unique IDs selected and choose Import.
  7. You can now view the ingested logs on the Discover page and visualizations on the Dashboards page, which you can find on the navigation bar.

    Figure 18: The Discover page displaying ingested logs

    Figure 18: The Discover page displaying ingested logs

Clean up

To avoid unwanted charges, delete the main CloudFormation template, named os-stack-<day>-<month> (not the nested stacks).

Figure 19: Select the main stack in the CloudFormation console

Figure 19: Select the main stack in the CloudFormation console

Modify the Security Lake bucket policy in the logging account to remove the section you added that trusted the PipelineRole. Be careful not to modify the rest of the policy because it could impact the functioning of Security Lake and other subscribers.

Figure 20: The S3 bucket policy with the relevant sections that needed to be deleted

Figure 20: The S3 bucket policy with the relevant sections that needed to be deleted

Conclusion

In this post, you learned how to plan an OpenSearch deployment with Amazon OpenSearch Service to ingest logs from Amazon Security Lake. With this solution, you’re able to aggregate and manage logs with Security Lake and visualize and monitor those logs with OpenSearch Service. After deployment, monitor the OpenSearch Service metrics to determine if you need to scale this up or out for improved performance. In part 2, I will show you how to set up the Security Analytics detector to generate alerts to security findings in near-real time.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Kevin Low
Kevin Low

Kevin is a Security Solutions Architect at AWS who helps the largest customers across ASEAN build securely. He specializes in threat detection and incident response and is passionate about integrating resilience and security. Outside of work, he loves spending time with his wife and dog, a poodle called Noodle.

Monitoring Apache Iceberg metadata layer using AWS Lambda, AWS Glue, and AWS CloudWatch

Post Syndicated from Michael Greenshtein original https://aws.amazon.com/blogs/big-data/monitoring-apache-iceberg-metadata-layer-using-aws-lambda-aws-glue-and-aws-cloudwatch/

In the era of big data, data lakes have emerged as a cornerstone for storing vast amounts of raw data in its native format. They support structured, semi-structured, and unstructured data, offering a flexible and scalable environment for data ingestion from multiple sources. Data lakes provide a unified repository for organizations to store and use large volumes of data. This enables more informed decision-making and innovative insights through various analytics and machine learning applications.

Despite their advantages, traditional data lake architectures often grapple with challenges such as understanding deviations from the most optimal state of the table over time, identifying issues in data pipelines, and monitoring a large number of tables. As data volumes grow, the complexity of maintaining operational excellence also increases. Monitoring and tracking issues in the data management lifecycle are essential for achieving operational excellence in data lakes.

This is where Apache Iceberg comes into play, offering a new approach to data lake management. Apache Iceberg is an open table format designed specifically to improve the performance, reliability, and scalability of data lakes. It addresses many of the shortcomings of traditional data lakes by providing features such as ACID transactions, schema evolution, row-level updates and deletes, and time travel.

In this blog post, we’ll discuss how the metadata layer of Apache Iceberg can be used to make data lakes more efficient. You will learn about an open-source solution that can collect important metrics from the Iceberg metadata layer. Based on collected metrics, we will provide recommendations on how to improve the efficiency of Iceberg tables. Additionally, you will learn how to use Amazon CloudWatch anomaly detection feature to detect ingestion issues.

Deep dive into Iceberg’s Metadata layer

Before diving into a solution, let’s understand how the Apache Iceberg metadata layer works. The Iceberg metadata layer provides an open specification instructing integrated big data engines such as Spark or Trino how to run read and write operations and how to resolve concurrency issues. It’s crucial for maintaining inter-operability between different engines. It stores detailed information about tables such as schema, partitioning, and file organization in versioned JSON and Avro files. This ensures that each change is tracked and reversible, enhancing data governance and auditability.

Apache Iceberg metadata layer architecture diagram

History and versioning: Iceberg’s versioning feature captures every change in table metadata as immutable snapshots, facilitating data integrity, historical views, and rollbacks.

File organization and snapshot management: Metadata closely manages data files, detailing file paths, formats, and partitions, supporting multiple file formats like Parquet, Avro, and ORC. This organization helps with efficient data retrieval through predicate pushdown, minimizing unnecessary data scans. Snapshot management allows concurrent data operations without interference, maintaining data consistency across transactions.

In addition to its core metadata management capabilities, Apache Iceberg also provides specialized metadata tables—snapshots, files, and partitions—that provide deeper insights and control over data management processes. These tables are dynamically generated and provide a live view of the metadata for query purposes, facilitating advanced data operations:

  • Snapshots table: This table lists all snapshots of a table, including snapshot IDs, timestamps, and operation types. It enables users to track changes over time and manage version history effectively.
  • Files table: The files table provides detailed information on each file in the table, including file paths, sizes, and partition values. It is essential for optimizing read and write performance.
  • Partitions table: This table shows how data is partitioned across different files and provides statistics for each partition, which is crucial for understanding and optimizing data distribution.

Metadata tables enhance Iceberg’s functionality by making metadata queries straightforward and efficient. Using these tables, data teams can gain precise control over data snapshots, file management, and partition strategies, further improving data system reliability and performance.

Before you get started

The next section describes a packaged open source solution using Apache Iceberg’s metadata layer and AWS services to enhance monitoring across your Iceberg tables.

Before we deep dive into the suggested solution, let’s mention Iceberg MetricsReporter, which is a native way to emit metrics for Apache Iceberg. It supports two types of reports: one for commits and one for scans. The default output is log based. It produces log files as a result of commit or scan operations. To submit metrics to CloudWatch or any other monitoring tool, users need to create and configure a custom MetricsReporter implementation. MetricsReporter is supported in Apache Iceberg v1.1.0 and later versions, and customers who want to use it must enable it through Spark configuration on their existing pipelines.

The following is deployed independently and doesn’t require any configuration changes to existing data pipelines. It can immediately start monitoring all the tables within the AWS account and AWS Region where it’s deployed. This solution introduces an additional latency of metrics arrival between 20 and 80 seconds compared to MetricsReporter but offers seamless integration without the need for custom configurations or changes to current workflows.

Solution overview

This solution is specifically designed for customers who run Apache Iceberg on Amazon Simple Storage Service (Amazon S3) and use AWS Glue as their data catalog.

Solution architecture diagram

Key features

This solution uses an AWS Lambda deployment package to collect metrics from Apache Iceberg tables. The metrics are then submitted to CloudWatch where you can create metrics visualizations to help recognize trends and anomalies over time.

The solution is designed to be lightweight, focusing on collecting metrics directly from the Iceberg metadata layer without scanning the actual data layer. This approach significantly reduces the compute capacity required, making it efficient and cost-effective. Key features of the solution include:

  • Time-series metrics collection: The solution monitors Iceberg tables continuously to identify trends and detect anomalies in data ingestion rates, partition skewness, and more.
  • Event-driven architecture: The solution uses Amazon EventBridge to launch a Lambda function when the state of an AWS Glue Data Catalog table changes. This ensures real-time metrics collection every time a transaction is committed to an Iceberg table.
  • Efficient data retrieval: Incorporates minimal compute resources by utilizing AWS Glue interactive sessions and the pyiceberg library to directly access Iceberg metadata tables such as snapshots, partitions, and files.

Metrics tracked

As of the blog release date, the solution collects over 25 metrics. These metrics are categorized into several groups:

  • Snapshot metrics: Include total and changes in data files, delete files, records added or removed, and size changes.
  • Partition and file metrics: Aggregated and per-partition metrics like average, maximum, minimum record counts and file sizes, which help in understanding data distribution and help optimizing storage.

To see the complete list of metrics, go to the GitHub repository.

Visualizing data with CloudWatch dashboards

The solution also provides a sample CloudWatch dashboard to visualize the collected metrics. Metrics visualization is important for real-time monitoring and detecting operational issues. The provided helper script simplifies the set up and deployment of the dashboard.

Amazon CloudWatch dashboard

You can go to the GitHub repository to learn more about how to deploy the solution in your AWS account.

What are the vital metrics for Apache Iceberg tables?

This section discusses specific metrics from Iceberg’s metadata and explains why they’re important for monitoring data quality and system performance. The metrics are broken down into three parts: insight, challenge, and action. This provides a clear path for practical application. In this section, we provide only a subset of the available metrics that the solution can collect, for a complete list, see the solution Github page.

1. snapshot.added_data_files, snapshot.added_records

  • Metric insight: The number of data files and number of records added to the table during the last transaction. The ingestion rate measures the speed at which new data is added to the data lake. This metric helps identify bottlenecks or inefficiencies in data pipelines, guiding capacity planning and scalability decisions.
  • Challenge: A sudden drop in the ingestion rate can indicate failures in data ingestion pipelines, source system outages, configuration errors or traffic spikes.
  • Action: Teams need to establish real-time monitoring and alert systems to detect drops in ingestion rates promptly, allowing quick investigations and resolutions.

2. files.avg_record_count, files.avg_file_size

  • Metric insight: These metrics provide insights into the distribution and storage efficiency of the table. Small file sizes might suggest excessive fragmentation.
  • Challenge: Excessively small file sizes can indicate inefficient data storage leading to increased read operations and higher I/O costs.
  • Action: Implementing regular data compaction processes helps consolidate small files, optimizing storage and enhancing content delivery speeds as demonstrated by a streaming service. Data Catalog offers automatic compaction of Apache Iceberg tables. To learn more about compacting Apache Iceberg tables, see Enable compaction in Working with tables on the AWS Glue console.

3. partitions.skew_record_count, partitions.skew_file_count

  • Metric insight: The metrics indicate the asymmetry of the data distribution across the available table partitions. A skewness value of zero, or very close to zero, suggests that the data is balanced. Positive or negative skewness values might indicate a problem.
  • Challenge: Imbalances in data distribution across partitions can lead to inefficiencies and slow query responses.
  • Action: Regularly analyze data distribution metrics to adjust partitioning configuration. Apache Iceberg allows you to transform partitions dynamically, which enables optimization of table partitioning as query patterns or data volumes change, without impacting your existing data.

4. snapshot.deleted_records, snapshot.total_delete_files, snapshot.added_position_deletes

  • Metric insight: Deletion metrics in Apache Iceberg provide important information on the volume and nature of data deletions within a table. These metrics help track how often data is removed or updated, which is essential for managing data lifecycle and compliance with data retention policies.
  • Challenge: High values in these metrics can indicate excessive deletions or updates, which might lead to fragmentation and decreased query performance.
  • Action: To address these challenges, run compaction periodically to ensure deleted rows do not persist in new files. Regularly review and adjust data retention policies and consider expiring old snapshots to keep only necessary amount of data files. You can run compaction operation on specific partitions using Amazon Athena Optimize

Effective monitoring is essential for making informed decisions about necessary maintenance actions for Apache Iceberg tables. Determining the right timing for these actions is crucial. Implementing timely preventative maintenance ensures high operational efficiency of the data lake and helps to address potential issues before they become significant problems.

Using Amazon CloudWatch for anomaly detection and alerts

This section assumes that you have completed the solution setup and collected operational metrics from your Apache Iceberg tables into Amazon CloudWatch.

Now you can start setting up some alerts and detect anomalies.

We guide you on setting up the anomaly detection and configuring alerts in CloudWatch to monitor the snapshot.added_records metric, which indicates the ingestion rate of data written into an Apache Iceberg table.

Set up anomaly detection

CloudWatch anomaly detection applies machine learning algorithms to continuously analyze system metrics, determine normal baselines, and identify items that are outside of the established patterns. Here is how you configure it:

Amazon CloudWatch anomaly detection screenshot

  1. Select Metrics: In the AWS Management Console for Cloudwatch, go to the Metrics  tab and search for and select snapshot.added_records.
  2. Create anomaly detection models: Choose the Graphed metrics tab and click the Pulse icon to enable anomaly detection.
  3. Set Sensitivity: The second parameter of the ANOMALY_DETECTION_BAND (m1, 5) is to adjust the sensitivity of the anomaly detection. The goal is to balance detecting real issues and reducing false positives.

Configure alerts

After the anomaly detection model is set up, set up an alert to notify operations teams about potential issues:

  1. Create alarm: Choose the bell icon under Actions on the same Graphed metrics tab.
  2. Alarm settings: Set the alarm to notify the operations team when the snapshot.added_records metric is outside the anomaly detection band for two consecutive periods. This helps reduce the risk of false alerts.
  3. Alarm actions: Configure CloudWatch to send an alarm email to the operations team. In addition to sending emails, CloudWatch alarm actions can automatically launch remediation processes, such as scaling operations or initiating data compaction.

Best practices

  • Regularly review and adjust models: As data patterns evolve, periodically review and adjust anomaly detection models and alarm settings to remain effective.
  • Comprehensive coverage: Ensure that all critical aspects of the data pipeline are monitored, not just a few metrics.
  • Documentation and communication: Maintain clear documentation of what each metric and alarm represent and ensure that your operations team understands the monitoring set up and response procedures. Set up the alerting mechanisms to send notifications through appropriate channels such as email, corporate messenger, or telephone to ensure your operations team stays informed and can quickly address the issues.
  • Create playbooks and automate remediation tasks: Establish detailed playbooks that describe step-by-step responses for common scenarios identified by alerts. Additionally, automate remediation tasks where possible to speed up response times and reduce the manual burden on teams. This ensures consistent and effective responses to all incidents.

CloudWatch anomaly detection and alerting features help organizations proactively manage their data lakes. This ensures data integrity, reduces downtime, and maintains high data quality. As a result, it enhances operational efficiency and supports robust data governance.

Conclusion

In this blog post, we explored Apache Iceberg’s transformative impact on data lake management. Apache Iceberg addresses the challenges of big data with features like ACID transactions, schema evolution, and snapshot isolation, enhancing data reliability, query performance, and scalability.

We delved into Iceberg’s metadata layer and related metadata tables such as snapshots, files, and partitions that allow easy access to crucial information about the current state of the table. These metadata tables facilitate the extraction of performance-related data, enabling teams to monitor and optimize the data lake’s efficiency.

Finally, we showed you a practical solution for monitoring Apache Iceberg tables using Lambda, AWS Glue, and CloudWatch. This solution uses Iceberg’s metadata layer and CloudWatch monitoring capabilities to provide a proactive operational framework. This framework detects trends and anomalies, ensuring robust data lake management.


About the Author

AvatarMichael Greenshtein is a Senior Analytics Specialist at Amazon Web Services. He is an experienced data professional with over 8 years in cloud computing and data management. Michael is passionate about open-source technology and Apache Iceberg.

Accelerate incident response with Amazon Security Lake – Part 2

Post Syndicated from Frank Phillis original https://aws.amazon.com/blogs/security/accelerate-incident-response-with-amazon-security-lake-part-2/

This blog post is the second of a two-part series where we show you how to respond to a specific incident by using Amazon Security Lake as the primary data source to accelerate incident response workflow. The workflow is described in the Unintended Data Access in Amazon S3 incident response playbook, published in the AWS incident response playbooks repository.

The first post in this series outlined prerequisite information and provided steps for setting up Security Lake. The post also highlighted how Security Lake can add value to your incident response capabilities and how that aligns with the National Institute of Standards and Technology (NIST) SP 800-61 Computer Security Incident Handling Guide. We demonstrated how you can set up Security Lake and related services in alignment with the AWS Security Reference Architecture (AWS SRA).

The following diagram shows the service architecture that we configured in the previous post. The highlighted services (Amazon Macie, Amazon GuardDuty, AWS CloudTrail, AWS Security Hub, Amazon Security Lake, Amazon Athena, and AWS Organizations) are relevant to the example referenced in this post, which focuses upon the phases of incident response outlined in NIST SP 800-61.

Figure 1: Example architecture configured in the previous blog post

Figure 1: Example architecture configured in the previous blog post

The first phase of the NIST SP 800-61 framework is preparation, which was covered in part 1 of this two-part blog series. The following sections cover phase 2 (detection and analysis) and phase 3 (containment, eradication, and recovery) of the NIST framework, and demonstrate how Security Lake accelerates your incident response workflow by providing a central datastore of security logs and findings in a standardized format.

Consider a scenario where your security team has received an Amazon GuardDuty alert through Amazon EventBridge for anomalous user behavior. As a result, the team becomes aware of potential unintended data access. GuardDuty noted unusual IAM user activity for the AWS Identity and Access Management (IAM) user Service_Backup and generated a finding. The security team had set up a rule in EventBridge that sends an alert email notifying them of GuardDuty findings relating to IAM user activity. At this point, the security team is unsure if any malicious activity has occurred, however, the username is not familiar. The security team should investigate further to determine whether the finding is a false positive by querying data in Security Lake. In line with the NIST incident response framework, the team moves to phase 2 of this investigation.

Phase 2: Acquire, preserve, and document evidence

The security team wants to investigate which API calls the unfamiliar user has been making. First, the team checks AWS CloudTrail management activity for the user, and they can do that by using Security Lake. They want a list of that user’s activity, which will help them in several ways:

  1. Give them a list of API calls that warrant further investigation (especially Create*)
  2. Give an indication whether the activity is unusual or not (in the context of “typical” user activity within the account, team, user group, or individual user)
  3. Give an indication of when potentially malicious activity might have started (user history)

The team can use Amazon Athena to query CloudTrail management events that were captured by Security Lake. In some cases, compromised user accounts might have existed for a long time previously as legitimate users and made tens of thousands of API calls. In such a case, how would a security team identify the calls that might need further investigation? A quick way to get a summary list of API calls the user has made would be to run a query like the following:

SELECT DISTINCT api.operation FROM amazon_security_lake_table_us_west_2_cloud_trail_mgmt_2_0
WHERE lower(actor.user.name) = 'service_backup'

From the results, the team can determine information and queries of interest to focus on for further investigation. To begin with, the security team uses the preceding query to enumerate the number and type of API calls made by the user, as shown in Figure 2.

Figure 2: Example API call summary made by an IAM user

Figure 2: Example API call summary made by an IAM user

The initial query results in Figure 2 show API calls that could indicate privilege elevation (creating users, attaching user policies, and similar calls are a good indicator). There are other API calls that indicate that additional resources may have been created, such as Amazon Simple Storage Service (Amazon S3) buckets and Amazon Elastic Compute Cloud (Amazon EC2) instances.

Note that in this early phase, the team didn’t time-bound the query. However, if there is a high degree of confidence that the team can focus on a specific time or date range, the query can be further modified. How would the team decide on a time period to focus on? When the team received the alert email from EventBridge, that email included information about the GuardDuty finding, including the time it was observed. The team can use that time as an anchor to search around.

The team now wants to look at the user’s activity in a bit more detail. To do that, they can use a query that returns more detail for each of the API calls the user has made:

SELECT time_dt AS "Time Date", metadata.product.name AS "Log Source", cloud.region, actor.user.type, actor.user.name, actor.user.account.uid AS "User AWS Acc ID", api.operation AS "API Operation", status AS "API Response", api.service.name AS "Service", api.request.data AS "Request Data"
FROM amazon_security_lake_table_us_west_2_cloud_trail_mgmt_2_0
WHERE lower(actor.user.name) = 'service_backup';
Figure 3: Example CloudTrail activity for an IAM user

Figure 3: Example CloudTrail activity for an IAM user

Figure 3 shows the result of the example query. The team observes that the user created an S3 bucket and performed other management plane actions, including creating IAM users and attaching the administrator access policy to a newly created user. Attempts were made to create other resources such as Amazon EC2 instances, but these were not successful. So the team needs to do further investigation on the newly created IAM users and S3 buckets, but they don’t need to take further action on EC2 instances, at least for this user.

The team starts to focus on investigating the IAM permissions of the Service_Backup user because some resources created by this user could lead to privilege elevation (for example: CreateUser >> AttachPolicy >> CreateAccessKey). The team verifies that the policy attached to that new user was AdminAccess. The activities of this newly created user should be investigated. Now, with a broad idea of that user’s activity and the time the activity occurred, the security team wants to focus on IAM activity, so that they can understand what resources have been created. Those resources will likely also need to be investigated.

The team can use the following query to find more detail about the resources that the user has created, modified, or deleted. In this case, the user has also created additional IAM users and roles. The team uses timestamps to limit query results to a specific time range during which they believe the suspicious activity occurred, and can also focus on IAM activity specifically.

SELECT time_dt AS "Time", cloud.region AS "Region", actor.session.issuer AS "Role Issuer", actor.user.name AS "User Name", api.operation AS "API Call", json_extract(api.request.data, '$.userName') AS "Target Principal", json_extract(api.request.data, '$.policyArn') AS "Target Policy", json_extract(api.request.data, '$.roleName') AS "Target Role", actor.user.uid AS "User ID", user.name AS "Target Principal", status AS "Response Status", accountid AS "AWS Account"
FROM amazon_security_lake_table_us_west_2_cloud_trail_mgmt_2_0
WHERE (lower(api.operation) LIKE 'create%' OR lower(api.operation) LIKE 'attach%' OR lower(api.operation) LIKE 'delete%')
AND lower(api.service.name) = 'iam.amazonaws.com'
AND lower(actor.user.name) = 'service_backup'
AND time_dt BETWEEN TIMESTAMP '2024-03-01 00:00:00.000' AND TIMESTAMP  '2024-05-31 23:59:00.000';
Figure 4: CloudTrail IAM activity for a specific user with additional resource detail

Figure 4: CloudTrail IAM activity for a specific user with additional resource detail

This additional detail helps the security team focus on the resources created by the Service_Backup user. These will need to be investigated further and most likely quarantined. If further analysis is required, resources can be disabled, or (in some instances) copied over to a forensic account to conduct the analysis.

Having identified newly created IAM resources that require further investigation, the team now continues by focusing on the resources created in S3. Has the Service_Backup user put objects into that bucket? Have they interacted with objects in any other buckets? To do that, the team queries the S3 data events by using Athena, as follows:

SELECT time_dt AS "Time Date", cloud.region AS "Region", actor.user.type, actor.user.name AS "User Name", api.operation AS "API Call", status AS "Status", api.request.data AS "Request Data", accountid AS "AWS Account ID"
FROM amazon_security_lake_table_us_west_2_s3_data_2_0
WHERE lower(actor.user.name) = 'service_backup';

The security team discovers that the Service_Backup user created an S3 bucket named breach.notify and uploaded a file named data-locked-xxx.txt in the bucket (the bucket name is also returned in the query results shown in Figure 3). Additionally, they see GetObject API calls for potentially sensitive data, followed by DeleteObject API calls for the same data and additional potentially sensitive data files. These are a group of CSV files, for example cc-data-2.csv, as shown in Figure 5.

Figure 5: Example Amazon S3 API activity for an IAM user

Figure 5: Example Amazon S3 API activity for an IAM user

Now the security team has two important goals:

  1. Protect and recover their data and resources
  2. Make sure that any applications that are reliant on those resources or data are available and serving customers

The security team knows that their S3 buckets do contain sensitive data, and they need a quick way to understand which files may be of value to a threat actor. Because the security team was able to quickly investigate their S3 data logs and determine that files have indeed been downloaded and deleted, they already have actionable information. To enrich that with additional context, the team needs a way to verify whether the file contains sensitive data. Amazon Macie can be configured to detect sensitive data in S3 buckets and natively integrate with Security Hub. The team had already configured Macie to scan their buckets and provide alerts if potentially sensitive data is discovered. The team can continue to use Athena to query Security Hub data stored in Security Lake, to see if the Macie results could be related to those files or buckets. The team looks for such findings that were generated around the time that the breach.notify S3 bucket was created, with the unusually named object uploaded, through the following Athena query:

SELECT time_dt AS "Date/Time", metadata.product.name AS "Log Source", cloud.account.uid AS "AWS Account ID", cloud.region AS "AWS Region", resources[1].type AS "Resource Type", resources[1].uid AS "Bucket ARN", resources[2].type AS "Resource Type 2", resources[2].uid AS "Object Name", finding_info.desc AS "Finding summary" FROM amazon_security_lake_table_us_west_2_sh_findings_2_0
WHERE cloud.account.uid = '<YOUR_AWS_ACCOUNT_ID>'
AND lower(metadata.product.name) = 'macie'
AND time_dt BETWEEN TIMESTAMP '2024-03-10 00:00:00.000' AND TIMESTAMP  '2024-03-14 23:59:00.000';
Figure 6: Example Amazon Macie finding summary for data in S3 buckets

Figure 6: Example Amazon Macie finding summary for data in S3 buckets

As Figure 6 shows, the team used the preceding query to pull just the information they needed to help them understand whether there is likely sensitive information in the bucket, which files contain that information, and what kind of information it is. From these results, it appears that the files listed do contain sensitive information, which appears to be credit card related data.

It’s time to stop and briefly review what the team now knows, and what still needs to be done. The team established that the Service_Backup user created additional IAM users and assigned wide-ranging permissions to those users. They also found that the Service_Backup user downloaded what appears to be confidential data, and then deleted those files from the customer’s buckets. Meanwhile, the Service_Backup user created a new S3 bucket and stored ransom files in it. In addition to this, that user also created IAM roles and attempted to create EC2 instances. In our example scenario, the first part of the investigation is complete.

There are a few things to note about what the team has done so far with Security Lake. First, because they’ve set up Security Lake across their entire organization, the team can query results from accounts in their organization, for various types of resources. That in itself saves a significant amount of time during the investigative process. Additionally, the team has seamlessly queried different sets of data to get an outcome—so far they have queried CloudTrail management events, S3 data events, and Macie findings through Security Hub—with the preceding queries done through Security Lake, directly from the Athena console, with no account or role switching, and no tool switching.

Next, we’ll move on to the containment step.

Phase 3: Containment, eradication, and recovery

Having gathered sufficient evidence in the previous phases to act, it’s now time for the team to contain this incident and focus on the AWS API by using either the AWS Management Console, the AWS CLI, or other tools. For the purposes of this blog post, we’ll use the CLI tools.

The team needs to perform several actions to contain the incident. They want to reduce the risk of further data exposure and the creation, modification, or deletion of resources in these AWS accounts. First, they will disable the Service_Backup user’s access and subsequently investigate and assess whether to disable the access of the IAM principal which created that user. Additionally, because Service_Backup created other IAM users, those users must also be investigated using the same process outlined earlier.

Next, the security team needs to determine whether or how they can restore the sensitive data that has been deleted from the bucket. If the bucket has versioning enabled, the act of deleting the object will result in the next most recent version becoming the current version. Alternatively, if they are using AWS Backup to protect their Amazon S3 data, they will be able to restore the most recently backed-up version. It’s worth noting that there could be other ways to restore that data—for example, the organization might have configured cross-Region replication for S3 buckets or other methods to protect their data.

After completing the steps to help prevent further access of the impacted IAM users, and restoring relevant data in impacted S3 buckets, the team now turns their attention to the additional resources created by the now-disabled user. Because these resources include IAM resources, the team needs a list of what has been created and deleted. They could see that information from earlier queries, but now decide to focus just on IAM resources by using the following example query;

SELECT time_dt AS "Time", cloud.region AS "Region", actor.session.issuer AS "Role Issuer", actor.user.name AS "User Name", api.operation AS "API Call", json_extract(api.request.data, '$.userName') AS "Target Principal", json_extract(api.request.data, '$.policyArn') AS "Target Policy", json_extract(api.request.data, '$.roleName') AS "Target Role", actor.user.uid AS "User ID", user.name AS "Target Principal", status AS "Response Status", accountid AS "AWS Account"
FROM amazon_security_lake_table_us_west_2_cloud_trail_mgmt_2_0
WHERE (lower(api.operation) LIKE 'create%' OR lower(api.operation) LIKE 'attach%' OR lower(api.operation) LIKE 'delete%')
AND lower(api.service.name) = 'iam.amazonaws.com'
AND time_dt BETWEEN TIMESTAMP '2024-03-01 00:00:00.000' AND TIMESTAMP  '2024-05-31 23:59:00.000';

This query returns a concise and informative list of activities for several users. There is a separate column for the role name or the user ID, corresponding to IAM roles and users, respectively, as shown in Figure 7.

Figure 7: IAM mutating API activity

Figure 7: IAM mutating API activity

The team uses the AWS CLI to revoke IAM role session credentials, to verify and, if necessary, to modify the role’s trust policy. They also capture an image of the EC2 instance for forensic analysis and terminate the instance. They will copy the data they want to save from the questionable S3 buckets and then delete the buckets, or at least remove the bucket policy.

After completing these tasks, the security team now confirms with the application owners that application recovery is complete or ongoing. They will subsequently review the event and undertake phase 4 of the NIST framework (post-incident activity) to find the root cause, look for opportunities for improvement, and work on remediating any configuration or design flaws that led to the initial breach.

Conclusion

This is the second post in a two-part series about accelerating security incident response with Security Lake. We used anomalous IAM user activity as an incident example to show how you can use Security Lake as a central repository for your security logs and findings, to accelerate the incident response process.

With Security Lake, your security team is empowered to use analytics tools like Amazon Athena to run queries against a central point of security logs and findings from various security data sources, including management logs and S3 data logs from AWS CloudTrail, Amazon Macie findings, Amazon GuardDuty findings, and more.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Frank Phillis

Frank Phillis
Frank is a Senior Solutions Architect (Security) at AWS. He enables customers to get their security architecture right. Frank specializes in cryptography, identity, and incident response. He’s the creator of the popular AWS Incident Response playbooks and regularly speaks at security events. When not thinking about tech, Frank can be found with his family, riding bikes, or making music.
You can follow Frank on LinkedIn.

Jerry Chen

Jerry Chen
Jerry is a Senior Cloud Optimization Success Solutions Architect at AWS. He focuses on cloud security and operational architecture design for AWS customers and partners.
You can follow Jerry on LinkedIn.

How to migrate your AWS CodeCommit repository to another Git provider

Post Syndicated from Rodney Bozo original https://aws.amazon.com/blogs/devops/how-to-migrate-your-aws-codecommit-repository-to-another-git-provider/

Customers can migrate their AWS CodeCommit Git repositories to other Git providers using several methods, such as cloning the repository, mirroring, or migrating specific branches. This blog describes a basic use case to mirror a repository to a generic provider, and links to instructions for mirroring to more specific providers. Your exact steps could vary depending on the type or complexity of your repository, and the decisions made on what and how you want to migrate. This post only describes how to migrate Git repository data, and does not describe exporting other data from CodeCommit such as pull requests.

Pre-requisites

  1. Before you can migrate your CodeCommit repository to another provider, make sure that you have the necessary credentials and permissions to both the AWS Management Console and the other provider’s account. For migrating to GitHub and Gitlab, use CodeCommit static credentials as described in HTTPS users using Git credentials. If you choose to use the generic migration option process described below, any type of CodeCommit credentials can be used. To learn more about setting up AWS CodeCommit access control see Setting up for AWS CodeCommit.
  2. In the AWS CodeCommit console, select the clone URL for the repository you will migrate. The correct clone URL (HTTPS, SSH, or HTTPS (CRC)) depends on which credential type and network protocol you have chosen to use.

Figure 1: Clone repositories

Migrating your AWS CodeCommit repository to a GitLab repository

Using the CodeCommit clone URL in combination with the HTTPS Git repository credentials, follow the guidance in GitLab’s documentation for importing source code from a repository by URL.

Migrating your AWS CodeCommit repository to a GitHub repository

Using the CodeCommit clone URL in combination with the HTTPS Git repository credentials, follow the guidance in GitHub’s documentation for importing source code.

Generic migration to a different repository provider

1.     Clone the AWS CodeCommit Repository
Clone the repository from AWS CodeCommit to your local machine using Git. If you’re using HTTPS, you can do this by running the following command:

git clone --mirror https://your-aws-repository-url your-aws-repository

Replace your-aws-repository-url with the URL of your AWS CodeCommit repository.
Replace your-aws-repository with a name for this repository. Example:

git clone https://git-codecommit.us-east-2.amazonaws.com/v1/repos/MyDemoRepo my-demo-repo

2.     Set up new remote repository

Navigate to the directory of your cloned AWS CodeCommit repository. Then, add the repository URL from the new repository provider as a remote:

git remote add <provider name> <provider-repository-url>

Replace <provider name> with the provider name of your choice. (Example: gitlab)
Replace <provider-repository-url> with the URL of your new repository provider’s repository.

3.     Push your local repository to the new remote repository

This will push all branches and tags to your new repository provider’s repository. The provider name must match the provider name from step 2.

git push <provider name> --mirror

Notes:

  • The remote repository should be empty
  • The remote repository may have protected branches not allowing force push. In this case, navigate to your new repository provider and disable branch protections to allow force push.

4.     Verify the Migration

Once the push is complete, verify that all files, branches, and tags have been successfully migrated to the new repository provider. You can do this by browsing your repository online or by cloning it to another location and checking it locally.

5.     Update Remote URLs

If you plan to continue working with the migrated repository locally, you may want to update the remote URL to point to the new provider’s repository instead of AWS CodeCommit. You can do this using the following command:

git remote set-url origin <provider-repository-url>

Replace <provider-repository-url> with the URL of your new repository provider’s repository.

6.     Update CI/CD Pipelines and fix protected branches

If you have CI/CD pipelines set up that interact with your repository, such as GitLab, GitHub or AWS CodePipeline, update their configuration to reflect the new repository URL. If you removed protected branch permissions in Step 3 you may want to add these back to your main branch.

7.     Inform Your Team

If you’re migrating a repository that others are working on, be sure to inform your team about the migration and provide them with the new repository URL.

8.     Delete the, now migrated, AWS CodeCommit repository

This action cannot be undone. Navigate back to the AWS CodeCommit console and delete the repository that you have migrated using the “Delete Repository” button.

Figure 2: Delete repositories

Conclusion

This post described a few methods to migrate your existing AWS CodeCommit repository to another Git provider. After migration, you have the option to continue to use your current AWS CodeCommit repository, but doing so will likely require a regular sync operation between AWS CodeCommit and the new repository provider. For more information about repository migration, please see the following resources:

Migrate a repository incrementally – This guide is written to migrate a repository to CodeCommit incrementally but can also be used for other Git providers.

Migrate from Apache Solr to OpenSearch

Post Syndicated from Aswath Srinivasan original https://aws.amazon.com/blogs/big-data/migrate-from-apache-solr-to-opensearch/

OpenSearch is an open source, distributed search engine suitable for a wide array of use-cases such as ecommerce search, enterprise search (content management search, document search, knowledge management search, and so on), site search, application search, and semantic search. It’s also an analytics suite that you can use to perform interactive log analytics, real-time application monitoring, security analytics and more. Like Apache Solr, OpenSearch provides search across document sets. OpenSearch also includes capabilities to ingest and analyze data. Amazon OpenSearch Service is a fully managed service that you can use to deploy, scale, and monitor OpenSearch in the AWS Cloud.

Many organizations are migrating their Apache Solr based search solutions to OpenSearch. The main driving factors include lower total cost of ownership, scalability, stability, improved ingestion connectors (such as Data Prepper, Fluent Bit, and OpenSearch Ingestion), elimination of external cluster managers like Zookeeper, enhanced reporting, and rich visualizations with OpenSearch Dashboards.

We recommend approaching a Solr to OpenSearch migration with a full refactor of your search solution to optimize it for OpenSearch. While both Solr and OpenSearch use Apache Lucene for core indexing and query processing, the systems exhibit different characteristics. By planning and running a proof-of-concept, you can ensure the best results from OpenSearch. This blog post dives into the strategic considerations and steps involved in migrating from Solr to OpenSearch.

Key differences

Solr and OpenSearch Service share fundamental capabilities delivered through Apache Lucene. However, there are some key differences in terminology and functionality between the two:

  • Collection and index: In OpenSearch, a collection is called an index.
  • Shard and replica: Both Solr and OpenSearch use the terms shard and replica.
  • API-driven Interactions: All interactions in OpenSearch are API-driven, eliminating the need for manual file changes or Zookeeper configurations. When creating an OpenSearch index, you define the mapping (equivalent to the schema) and the settings (equivalent to solrconfig) as part of the index creation API call.

Having set the stage with the basics, let’s dive into the four key components and how each of them can be migrated from Solr to OpenSearch.

Collection to index

A collection in Solr is called an index in OpenSearch. Like a Solr collection, an index in OpenSearch also has shards and replicas.

Although the shard and replica concept is similar in both the search engines, you can use this migration as a window to adopt a better sharding strategy. Size your OpenSearch shards, replicas, and index by following the shard strategy best practices.

As part of the migration, reconsider your data model. In examining your data model, you can find efficiencies that dramatically improve your search latencies and throughput. Poor data modeling doesn’t only result in search performance problems but extends to other areas. For example, you might find it challenging to construct an effective query to implement a particular feature. In such cases, the solution often involves modifying the data model.

Differences: Solr allows primary shard and replica shard collocation on the same node. OpenSearch doesn’t place the primary and replica on the same node. OpenSearch Service zone awareness can automatically ensure that shards are distributed to different Availability Zones (data centers) to further increase resiliency.

The OpenSearch and Solr notions of replica are different. In OpenSearch, you define a primary shard count using number_of_primaries that determines the partitioning of your data. You then set a replica count using number_of_replicas. Each replica is a copy of all the primary shards. So, if you set number_of_primaries to 5, and number_of_replicas to 1, you will have 10 shards (5 primary shards, and 5 replica shards). Setting replicationFactor=1 in Solr yields one copy of the data (the primary).

For example, the following creates a collection called test with one shard and no replicas.

http://localhost:8983/solr/admin/collections?
  _=action=CREATE
  &maxShardsPerNode=2
  &name=test
  &numShards=1
  &replicationFactor=1
  &wt=json

In OpenSearch, the following creates an index called test with five shards and one replica

PUT test
{
  "settings": {
    "number_of_shards": 5,
    "number_of_replicas": 1
  }
}

Schema to mapping

In Solr schema.xml OR managed-schema has all the field definitions, dynamic fields, and copy fields along with field type (text analyzers, tokenizers, or filters). You use the schema API to manage schema. Or you can run in schema-less mode.

OpenSearch has dynamic mapping, which behaves like Solr in schema-less mode. It’s not necessary to create an index beforehand to ingest data. By indexing data with a new index name, you create the index with OpenSearch managed service default settings (for example: "number_of_shards": 5, "number_of_replicas": 1) and the mapping based on the data that’s indexed (dynamic mapping).

We strongly recommend you opt for a pre-defined strict mapping. OpenSearch sets the schema based on the first value it sees in a field. If a stray numeric value is the first value for what is really a string field, OpenSearch will incorrectly map the field as numeric (integer, for example). Subsequent indexing requests with string values for that field will fail with an incorrect mapping exception. You know your data, you know your field types, you will benefit from setting the mapping directly.

Tip: Consider performing a sample indexing to generate the initial mapping and then refine and tidy up the mapping to accurately define the actual index. This approach helps you avoid manually constructing the mapping from scratch.

For Observability workloads, you should consider using Simple Schema for Observability. Simple Schema for Observability (also known as ss4o) is a standard for conforming to a common and unified observability schema. With the schema in place, Observability tools can ingest, automatically extract, and aggregate data and create custom dashboards, making it easier to understand the system at a higher level.

Many of the field types (data types), tokenizers, and filters are the same in both Solr and OpenSearch. After all, both use Lucene’s Java search library at their core.

Let’s look at an example:

<!-- Solr schema.xml snippets -->
<field name="id" type="string" indexed="true" stored="true" required="true" multiValued="false" /> 
<field name="name" type="string" indexed="true" stored="true" multiValued="true"/>
<field name="address" type="text_general" indexed="true" stored="true"/>
<field name="user_token" type="string" indexed="false" stored="true"/>
<field name="age" type="pint" indexed="true" stored="true"/>
<field name="last_modified" type="pdate" indexed="true" stored="true"/>
<field name="city" type="text_general" indexed="true" stored="true"/>

<uniqueKey>id</uniqueKey>

<copyField source="name" dest="text"/>
<copyField source="address" dest="text"/>

<fieldType name="string" class="solr.StrField" sortMissingLast="true" />
<fieldType name="pint" class="solr.IntPointField" docValues="true"/>
<fieldType name="pdate" class="solr.DatePointField" docValues="true"/>

<fieldType name="text_general" class="solr.TextField" positionIncrementGap="100">
<analyzer type="index">
    <tokenizer class="solr.StandardTokenizerFactory"/>
    <filter class="solr.ASCIIFoldingFilterFactory" preserveOriginal="false" />
    <filter class="solr.LowerCaseFilterFactory"/>
</analyzer>
<analyzer type="query">
    <tokenizer class="solr.StandardTokenizerFactory"/>
    <filter class="solr.ASCIIFoldingFilterFactory" preserveOriginal="false" />
    <filter class="solr.LowerCaseFilterFactory"/>
</analyzer>
</fieldType>
PUT index_from_solr
{
  "settings": {
    "analysis": {
      "analyzer": {
        "text_general": {
          "type": "custom",
          "tokenizer": "standard",
          "filter": [
            "lowercase",
            "asciifolding"
          ]
        }
      }
    }
  },
  "mappings": {
    "properties": {
      "name": {
        "type": "keyword",
        "copy_to": "text"
      },
      "address": {
        "type": "text",
        "analyzer": "text_general"
      },
      "user_token": {
        "type": "keyword",
        "index": false
      },
      "age": {
        "type": "integer"
      },
      "last_modified": {
        "type": "date"
      },
      "city": {
        "type": "text",
        "analyzer": "text_general"
      },
      "text": {
        "type": "text",
        "analyzer": "text_general"
      }
    }
  }
}

Notable things in OpenSearch compared to Solr:

  1. _id is always the uniqueKey and cannot be defined explicitly, because it’s always present.
  2. Explicitly enabling multivalued isn’t necessary because any OpenSearch field can contain zero or more values.
  3. The mapping and the analyzers are defined during index creation. New fields can be added and certain mapping parameters can be updated later. However, deleting a field isn’t possible. A handy ReIndex API can overcome this problem. You can use the Reindex API to index data from one index to another.
  4. By default, analyzers are for both index and query time. For some less-common scenarios, you can change the query analyzer at search time (in the query itself), which will override the analyzer defined in the index mapping and settings.
  5. Index templates are also a great way to initialize new indexes with predefined mappings and settings. For example, if you continuously index log data (or any time-series data), you can define an index template so that all the indices have the same number of shards and replicas. It can also be used for dynamic mapping control and component templates

Look for opportunities to optimize the search solution. For instance, if the analysis reveals that the city field is solely used for filtering rather than searching, consider changing its field type to keyword instead of text to eliminate unnecessary text processing. Another optimization could involve disabling doc_values for the user_token field if it’s only intended for display purposes. doc_values are disabled by default for the text datatype.

SolrConfig to settings

In Solr, solrconfig.xml carries the collection configuration. All sorts of configurations pertaining to everything from index location and formatting, caching, codec factory, circuit breaks, commits and tlogs all the way up to slow query config, request handlers, and update processing chain, and so on.

Let’s look at an example:

<codecFactory class="solr.SchemaCodecFactory">
<str name="compressionMode">`BEST_COMPRESSION`</str>
</codecFactory>

<autoCommit>
    <maxTime>${solr.autoCommit.maxTime:15000}</maxTime>
    <openSearcher>false</openSearcher>
</autoCommit>

<autoSoftCommit>
    <maxTime>${solr.autoSoftCommit.maxTime:-1}</maxTime>
    </autoSoftCommit>

<slowQueryThresholdMillis>1000</slowQueryThresholdMillis>

<maxBooleanClauses>${solr.max.booleanClauses:2048}</maxBooleanClauses>

<requestHandler name="/query" class="solr.SearchHandler">
    <lst name="defaults">
    <str name="echoParams">explicit</str>
    <str name="wt">json</str>
    <str name="indent">true</str>
    <str name="df">text</str>
    </lst>
</requestHandler>

<searchComponent name="spellcheck" class="solr.SpellCheckComponent"/>
<searchComponent name="suggest" class="solr.SuggestComponent"/>
<searchComponent name="elevator" class="solr.QueryElevationComponent"/>
<searchComponent class="solr.HighlightComponent" name="highlight"/>

<queryResponseWriter name="json" class="solr.JSONResponseWriter"/>
<queryResponseWriter name="velocity" class="solr.VelocityResponseWriter" startup="lazy"/>
<queryResponseWriter name="xslt" class="solr.XSLTResponseWriter"/>

<updateRequestProcessorChain name="script"/>

Notable things in OpenSearch compared to Solr:

  1. Both OpenSearch and Solr have BEST_SPEED codec as default (LZ4 compression algorithm). Both offer BEST_COMPRESSION as an alternative. Additionally OpenSearch offers zstd and zstd_no_dict. Benchmarking for different compression codecs is also available.
  2. For near real-time search, refresh_interval needs to be set. The default is 1 second which is good enough for most use cases. We recommend increasing refresh_interval to 30 or 60 seconds to improve indexing speed and throughput, especially for batch indexing.
  3. Max boolean clause is a static setting, set at node level using the indices.query.bool.max_clause_count setting.
  4. You don’t need an explicit requestHandler. All searches use the _search or _msearch endpoint. If you’re used to using the requestHandler with default values then you can use search templates.
  5. If you’re used to using /sql requestHandler, OpenSearch also lets you use SQL syntax for querying and has a Piped Processing Language.
  6. Spellcheck, also known as Did-you-mean, QueryElevation (known as pinned_query in OpenSearch), and highlighting are all supported during query time. You don’t need to explicitly define search components.
  7. Most API responses are limited to JSON format, with CAT APIs as the only exception. In cases where Velocity or XSLT is used in Solr, it must be managed on the application layer. CAT APIs respond in JSON, YAML, or CBOR formats.
  8. For the updateRequestProcessorChain, OpenSearch provides the ingest pipeline, allowing the enrichment or transformation of data before indexing. Multiple processor stages can be chained to form a pipeline for data transformation. Processors include GrokProcessor, CSVParser, JSONProcessor, KeyValue, Rename, Split, HTMLStrip, Drop, ScriptProcessor, and more. However, it’s strongly recommended to do the data transformation outside OpenSearch. The ideal place to do that would be at OpenSearch Ingestion, which provides a proper framework and various out-of-the-box filters for data transformation. OpenSearch Ingestion is built on Data Prepper, which is a server-side data collector capable of filtering, enriching, transforming, normalizing, and aggregating data for downstream analytics and visualization.
  9. OpenSearch also introduced search pipelines, similar to ingest pipelines but tailored for search time operations. Search pipelines make it easier for you to process search queries and search results within OpenSearch. Currently available search processors include filter query, neural query enricher, normalization, rename field, scriptProcessor, and personalize search ranking, with more to come.
  10. The following image shows how to set refresh_interval and slowlog. It also shows you the other possible settings.
  11. Slow logs can be set like the following image but with much more precision with separate thresholds for the query and fetch phases.

Before migrating every configuration setting, assess if the setting can be adjusted based on your current search system experience and best practices. For instance, in the preceding example, the slow logs threshold of 1 second might be intensive for logging, so that can be revisited. In the same example, max.booleanClauses might be another thing to look at and reduce.

Differences: Some settings are done at the cluster level or node level and not at the index level. Including settings such as max boolean clause, circuit breaker settings, cache settings, and so on.

Rewriting queries

Rewriting queries deserves its own blog post; however we want to at least showcase the autocomplete feature available in OpenSearch Dashboards, which helps ease query writing.

Similar to the Solr Admin UI, OpenSearch also features a UI called OpenSearch Dashboards. You can use OpenSearch Dashboards to manage and scale your OpenSearch clusters. Additionally, it provides capabilities for visualizing your OpenSearch data, exploring data, monitoring observability, running queries, and so on. The equivalent for the query tab on the Solr UI in OpenSearch Dashboard is Dev Tools. Dev Tools is a development environment that lets you set up your OpenSearch Dashboards environment, run queries, explore data, and debug problems.

Now, let’s construct a query to accomplish the following:

  1. Search for shirt OR shoe in an index.
  2. Create a facet query to find the number of unique customers. Facet queries are called aggregation queries in OpenSearch. Also known as aggs query.

The Solr query would look like this:

http://localhost:8983/solr/solr_sample_data_ecommerce/select?q=shirt OR shoe
  &facet=true
  &facet.field=customer_id
  &facet.limit=-1
  &facet.mincount=1
  &json.facet={
   unique_customer_count:"unique(customer_id)"
  }

The image below demonstrates how to re-write the above Solr query into an OpenSearch query DSL:

Conclusion

OpenSearch covers a wide variety of uses cases, including enterprise search, site search, application search, ecommerce search, semantic search, observability (log observability, security analytics (SIEM), anomaly detection, trace analytics), and analytics. Migration from Solr to OpenSearch is becoming a common pattern. This blog post is designed to be a starting point for teams seeking guidance on such migrations.

You can try out OpenSearch with the OpenSearch Playground. You can get started with Amazon OpenSearch Service, a managed implementation of OpenSearch in the AWS Cloud.


About the Authors

Aswath Srinivasan is a Senior Search Engine Architect at Amazon Web Services currently based in Munich, Germany. With over 17 years of experience in various search technologies, Aswath currently focuses on OpenSearch. He is a search and open-source enthusiast and helps customers and the search community with their search problems.
Jon Handler is a Senior Principal Solutions Architect at Amazon Web Services based in Palo Alto, CA. Jon works closely with OpenSearch and Amazon OpenSearch Service, providing help and guidance to a broad range of customers who have search and log analytics workloads that they want to move to the AWS Cloud. Prior to joining AWS, Jon’s career as a software developer included 4 years of coding a large-scale, ecommerce search engine. Jon holds a Bachelor of the Arts from the University of Pennsylvania, and a Master of Science and a PhD in Computer Science and Artificial Intelligence from Northwestern University.
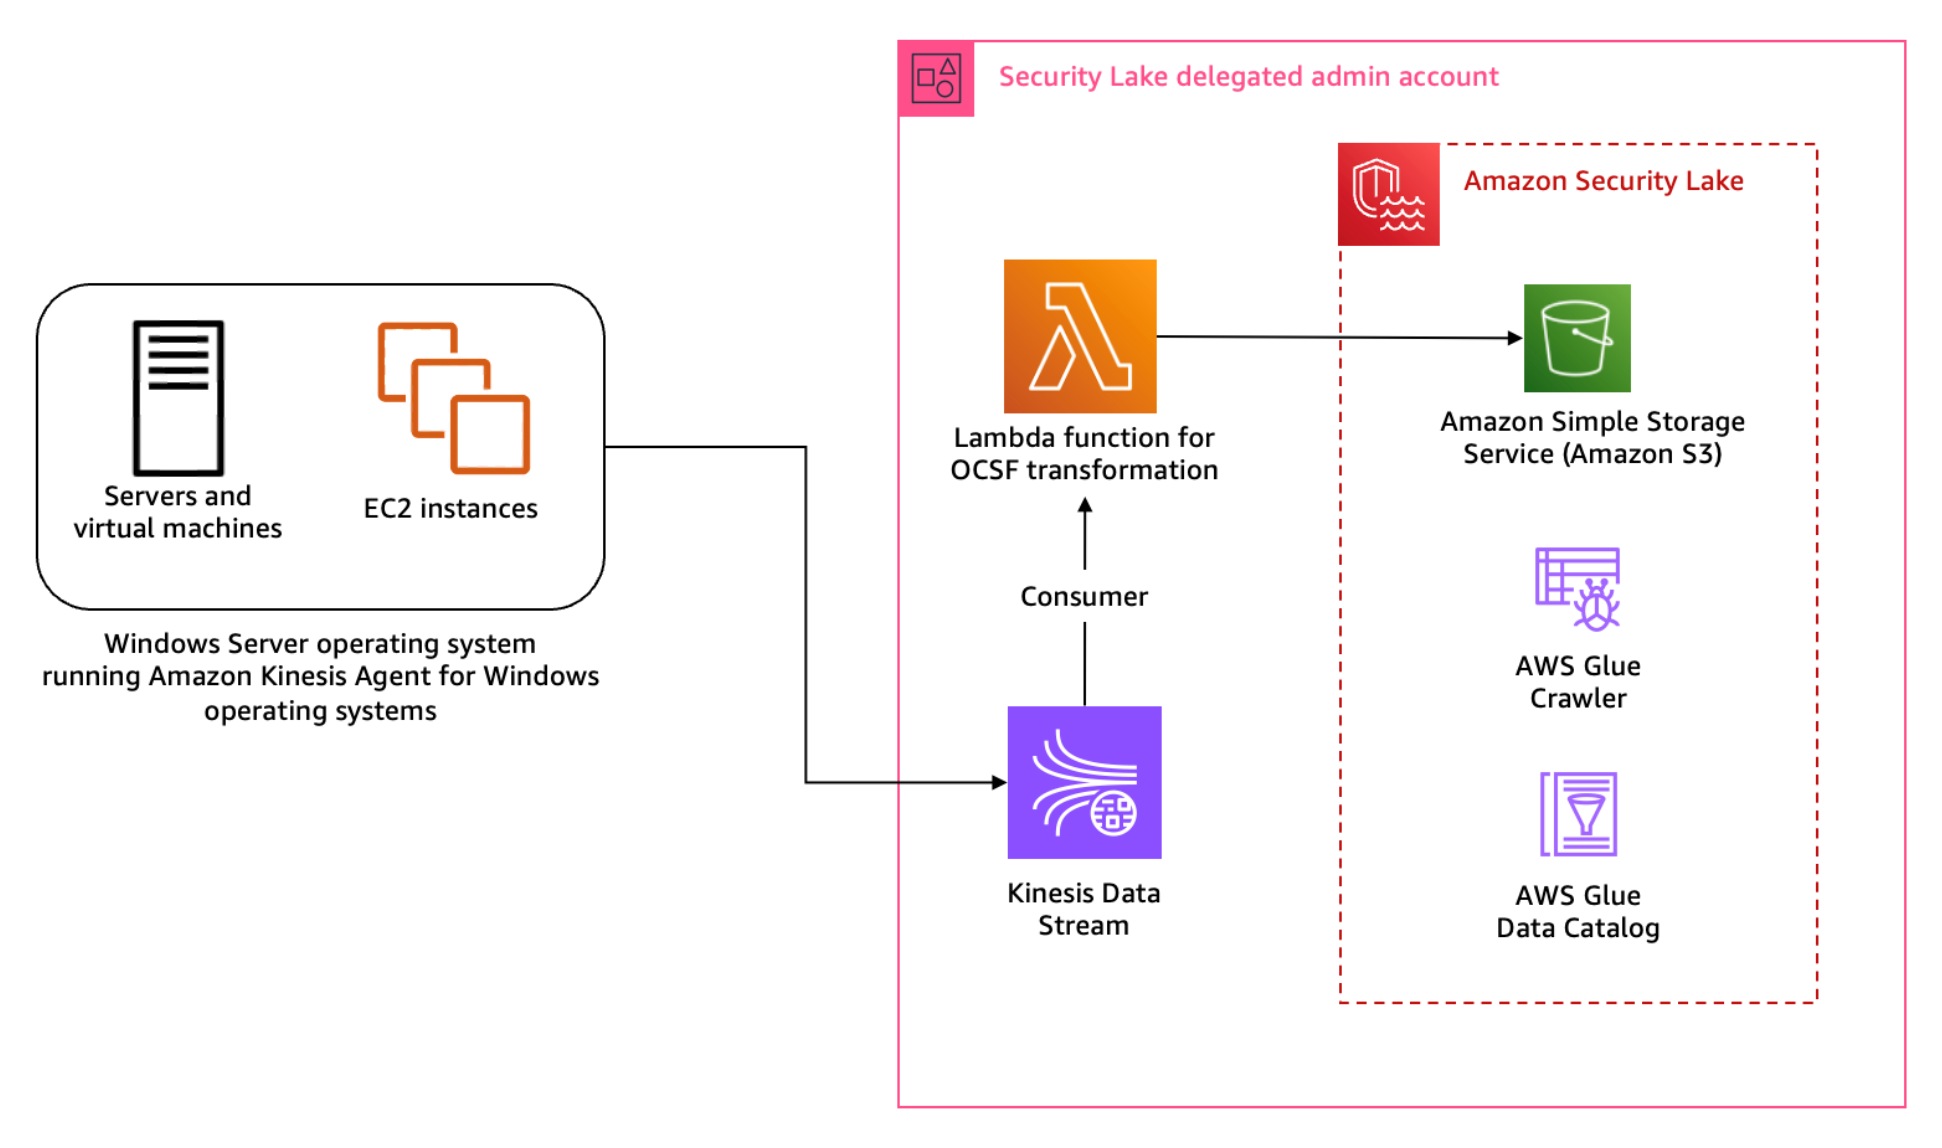
Patterns for consuming custom log sources in Amazon Security Lake

Post Syndicated from Pratima Singh original https://aws.amazon.com/blogs/security/patterns-for-consuming-custom-log-sources-in-amazon-security-lake/

As security best practices have evolved over the years, so has the range of security telemetry options. Customers face the challenge of navigating through security-relevant telemetry and log data produced by multiple tools, technologies, and vendors while trying to monitor, detect, respond to, and mitigate new and existing security issues. In this post, we provide you with three patterns to centralize the ingestion of log data into Amazon Security Lake, regardless of the source. You can use the patterns in this post to help streamline the extract, transform and load (ETL) of security log data so you can focus on analyzing threats, detecting anomalies, and improving your overall security posture. We also provide the corresponding code and mapping for the patterns in the amazon-security-lake-transformation-library.

Security Lake automatically centralizes security data into a purpose-built data lake in your organization in AWS Organizations. You can use Security Lake to collect logs from multiple sources, including natively supported AWS services, Software-as-a-Service (SaaS) providers, on-premises systems, and cloud sources.

Centralized log collection in a distributed and hybrid IT environment can help streamline the process, but log sources generate logs in disparate formats. This leads to security teams spending time building custom queries based on the schemas of the logs and events before the logs can be correlated for effective incident response and investigation. You can use the patterns presented in this post to help build a scalable and flexible data pipeline to transform log data using Open Cybersecurity Schema Framework (OCSF) and stream the transformed data into Security Lake.

Security Lake custom sources

You can configure custom sources to bring your security data into Security Lake. Enterprise security teams spend a significant amount of time discovering log sources in various formats and correlating them for security analytics. Custom source configuration helps security teams centralize distributed and disparate log sources in the same format. Security data in Security Lake is centralized and normalized into OCSF and compressed in open source, columnar Apache Parquet format for storage optimization and query efficiency. Having log sources in a centralized location and in a single format can significantly improve your security team’s timelines when performing security analytics. With Security Lake, you retain full ownership of the security data stored in your account and have complete freedom of choice for analytics. Before discussing creating custom sources in detail, it’s important to understand the OCSF core schema, which will help you map attributes and build out the transformation functions for the custom sources of your choice.

Understanding the OCSF

OCSF is a vendor-agnostic and open source standard that you can use to address the complex and heterogeneous nature of security log collection and analysis. You can extend and adapt the OCSF core security schema for a range of use cases in your IT environment, application, or solution while complementing your existing security standards and processes. As of this writing, the most recent major version release of the schema is v1.2.0, which contains six categories: System Activity, Findings, Identity and Access Management, Network Activity, Discovery, and Application Activity. Each category consists of different classes based on the type of activity, and each class has a unique class UID. For example, File System Activity has a class UID of 1001.

As of this writing, Security Lake (version 1) supports OCSF v1.1.0. As Security Lake continues to support newer releases of OCSF, you can continue to use the patterns from this post. However, you should revisit the mappings in case there’s a change in the classes you’re using.

Prerequisites

You must have the following prerequisites for log ingestion into Amazon Security Lake. Each pattern has a sub-section of prerequisites that are relevant to the data pipeline for the custom log source.

  1. AWS Organizations is configured your AWS environment. AWS Organizations is an AWS account management service that provides account management and consolidated billing capabilities that you can use to consolidate multiple AWS accounts and manage them centrally.
  2. Security Lake is activated and a delegated administrator is configured.
    1. Open the AWS Management Console and navigate to AWS Organizations. Set up an organization with a Log Archive account. The Log Archive account should be used as the delegated Security Lake administrator account where you will configure Security Lake. For more information on deploying the full complement of AWS security services in a multi-account environment, see AWS Security Reference Architecture.
    2. Configure permissions for the Security Lake administrator access by using an AWS Identity and Access Management (IAM) role. This role should be used by your security teams to administer Security Lake configuration, including managing custom sources.
    3. Enable Security Lake in the AWS Region of your choice in the Log Archive account. When you configure Security Lake, you can define your collection objectives, including log sources, the Regions that you want to collect the log sources from, and the lifecycle policy you want to assign to the log sources. Security Lake uses Amazon Simple Storage Service (Amazon S3) as the underlying storage for the log data. Amazon S3 is an object storage service offering industry-leading scalability, data availability, security, and performance. S3 is built to store and retrieve data from practically anywhere. Security Lake creates and configures individual S3 buckets in each Region identified in the collection objectives in the Log Archive account.

Transformation library

With this post, we’re publishing the amazon-security-lake-transformation-library project to assist with mapping custom log sources. The transformation code is deployed as an AWS Lambda function. You will find the deployment automation using AWS CloudFormation in the solution repository.

To use the transformation library, you should understand how to build the mapping configuration file. The mapping configuration file holds mapping information from raw events to OCSF formatted logs. The transformation function builds the OCSF formatted logs based on the attributes mapped in the file and streams them to the Security Lake S3 buckets.

The solution deployment is a four-step process:

  1. Update mapping configuration
  2. Add a custom source in Security Lake
  3. Deploy the log transformation infrastructure
  4. Update the default AWS Glue crawler

The mapping configuration file is a JSON-formatted file that’s used by the transformation function to evaluate the attributes of the raw logs and map them to the relevant OCSF class attributes. The configuration is based on the mapping identified in Table 3 (File System Activity class mapping) and extended to the Process Activity class. The file uses the $. notation to identify attributes that the transformation function should evaluate from the event.

{  "custom_source_events": {
        "source_name": "windows-sysmon",
        "matched_field": "$.EventId",
        "ocsf_mapping": {
            "1": {
                "schema": "process_activity",
                "schema_mapping": {   
                    "metadata": {
                        "profiles": "host",
                        "version": "v1.1.0",
                        "product": {
                            "name": "System Monitor (Sysmon)",
                            "vendor_name": "Microsoft Sysinternals",
                            "version": "v15.0"
                        }
                    },
                    "severity": "Informational",
                    "severity_id": 1,
                    "category_uid": 1,
                    "category_name": "System Activity",
                    "class_uid": 1007,
                    "class_name": "Process Activity",
                    "type_uid": 100701,
                    "time": "$.Description.UtcTime",
                    "activity_id": {
                        "enum": {
                            "evaluate": "$.EventId",
                            "values": {
                                "1": 1,
                                "5": 2,
                                "7": 3,
                                "10": 3,
                                "19": 3,
                                "20": 3,
                                "21": 3,
                                "25": 4
                            },
                            "other": 99
                        }
                    },
                    "actor": {
                        "process": "$.Description.Image"
                    },
                    "device": {
                        "type_id": 6,
                        "instance_uid": "$.UserDefined.source_instance_id"
                    },
                    "process": {
                        "pid": "$.Description.ProcessId",
                        "uid": "$.Description.ProcessGuid",
                        "name": "$.Description.Image",
                        "user": "$.Description.User",
                        "loaded_modules": "$.Description.ImageLoaded"
                    },
                    "unmapped": {
                        "rulename": "$.Description.RuleName"
                    }
                    
                }
            },
…
…
…
        }
    }
}

Configuration in the mapping file is stored under the custom_source_events key. You must keep the value for the key source_name the same as the name of the custom source you add for Security Lake. The matched_field is the key that the transformation function uses to iterate over the log events. The iterator (1), in the preceding snippet, is the Sysmon event ID and the data structure that follows is the OCSF attribute mapping.

Some OCSF attributes are of an Object data type with a map of pre-defined values based on the event signature such as activity_id. You represent such attributes in the mapping configuration as shown in the following example:

'activity_id': {
    'enum': {
        'evaluate': '$.EventId',
        'values': {
              2: 6,
              11: 1,
              15: 1,
              24: 3,
              23: 4
         },
         'other': 99
      }
 }

In the preceding snippet, you can see the words enum and evaluate. These keywords tell the underlying mapping function that the result will be the value from the map defined in values and the key to evaluate is the EventId, which is listed as the value of the evaluate key. You can build your own transformation function based on your custom sources and mapping or you can extend the function provided in this post.

Pattern 1: Log collection in a hybrid environment using Kinesis Data Streams

The first pattern we discuss in this post is the collection of log data from hybrid sources such as operating system logs collected from Microsoft Windows operating systems using System Monitor (Sysmon). Sysmon is a service that monitors and logs system activity to the Windows event log. It’s one of the log collection tools used by customers in a Windows Operating System environment because it provides detailed information about process creations, network connections, and file modifications This host-level information can prove crucial during threat hunting scenarios and security analytics.

Solution overview

The solution for this pattern uses Amazon Kinesis Data Streams and Lambda to implement the schema transformation. Kinesis Data Streams is a serverless streaming service that makes it convenient to capture and process data at any scale. You can configure stream consumers—such as Lambda functions—to operate on the events in the stream and convert them into required formats—such as OCSF—for analysis without maintaining processing infrastructure. Lambda is a serverless, event-driven compute service that you can use to run code for a range of applications or backend services without provisioning or managing servers. This solution integrates Lambda with Kinesis Data Streams to launch transformation tasks on events in the stream.

To stream Sysmon logs from the host, you use Amazon Kinesis Agent for Microsoft Windows. You can run this agent on fleets of Windows servers hosted on-premises or in your cloud environment.

Figure 1: Architecture diagram for Sysmon event logs custom source

Figure 1: Architecture diagram for Sysmon event logs custom source

Figure 1 shows the interaction of services involved in building the custom source ingestion. The servers and instances generating logs run the Kinesis Agent for Windows to stream log data to the Kinesis Data Stream which invokes a consumer Lambda function. The Lambda function transforms the log data into OCSF based on the mapping provided in the configuration file and puts the transformed log data into Security Lake S3 buckets. We cover the solution implementation later in this post, but first let’s review how you can map Sysmon event streaming through Kinesis Data Streams into the relevant OCSF classes. You can deploy the infrastructure using the AWS Serverless Application Model (AWS SAM) template provided in the solution code. AWS SAM is an extension of the AWS Command Line Interface (AWS CLI), which adds functionality for building and testing applications using Lambda functions.

Mapping

Windows Sysmon events map to various OCSF classes. To build the transformation of the Sysmon events, work through the mapping of events with relevant OCSF classes. The latest version of Sysmon (v15.14) defines 30 events including a catch-all error event.

Sysmon eventID Event detail Mapped OCSF class
1 Process creation Process Activity
2 A process changed a file creation time File System Activity
3 Network connection Network Activity
4 Sysmon service state changed Process Activity
5 Process terminated Process Activity
6 Driver loaded Kernel Activity
7 Image loaded Process Activity
8 CreateRemoteThread Network Activity
9 RawAccessRead Memory Activity
10 ProcessAccess Process Activity
11 FileCreate File System Activity
12 RegistryEvent (Object create and delete) File System Activity
13 RegistryEvent (Value set) File System Activity
14 RegistryEvent (Key and value rename) File System Activity
15 FileCreateStreamHash File System Activity
16 ServiceConfigurationChange Process Activity
17 PipeEvent (Pipe created) File System Activity
18 PipeEvent (Pipe connected) File System Activity
19 WmiEvent (WmiEventFilter activity detected) Process Activity
20 WmiEvent (WmiEventConsumer activity detected) Process Activity
21 WmiEvent (WmiEventConsumerToFilter activity detected) Process Activity
22 DNSEvent (DNS query) DNS Activity
23 FileDelete (File delete archived) File System Activity
24 ClipboardChange (New content in the clipboard) File System Activity
25 ProcessTampering (Process image change) Process Activity
26 FileDeleteDetected (File delete logged) File System Activity
27 FileBlockExecutable File System Activity
28 FileBlockShredding File System Activity
29 FileExecutableDetected File System Activity
255 Sysmon error Process Activity

Table 1: Sysmon event mapping with OCSF (v1.1.0) classes

Start by mapping the Sysmon events to the relevant OCSF classes in plain text as shown in Table 1 before adding them to the mapping configuration file for the transformation library. This mapping is flexible; you can choose to map an event to a different event class depending on the standard defined within the security engineering function. Based on our mapping, Table 1 indicates that a majority of the events reported by Sysmon align with the File System Activity or the Process Activity class. Registry events map better with the Registry Key Activity and Registry Value Activity classes, but these classes are deprecated in OCSF v1.0.0, so we recommend using File System Activity instead of registry events for compatibility with future versions of OCSF. You can be selective about the events captured and reported by Sysmon by altering the Sysmon configuration file. For this post, we’re using the sysmonconfig.xml published in the sysmon-modular project. The project provides a modular configuration along with publishing tactics, techniques, and procedures (TTPs) with Sysmon events to help in TTP-based threat hunting use cases. If you have your own curated Sysmon configuration, you can use that. While this solution offers mapping advice, if you’re using your own Sysmon configuration, you should make sure that you’re mapping the relevant attributes using this solution as a guide. As a best practice, mapping should be non-destructive to keep your information after the OCSF transformation. If there are attributes in the log data that you cannot map to an available attribute in the OCSF class, then you should use the unmapped attribute to collect all such information. In this pattern, RuleName captures the TTPs associated with the Sysmon event, because TTPs don’t map to a specific attribute within OCSF.

Across all classes in OCSF, there are some common attributes that are mandatory. The common mandatory attributes are mapped shown in Table 2. You need to set these attributes regardless of the OCSF class you’re transforming the log data to.

OCSF Raw
metadata.profiles [host]
metadata.version v1.1.0
metadata.product.name System Monitor (Sysmon)
metadata.product.vendor_name Microsoft Sysinternals
metadata.product.version v15.14
severity Informational
severity_id 1

Table 2: Mapping mandatory attributes

Each OCSF class has its own schema, which is extendable. After mapping the common attributes, you can map the attributes in the File System Activity class relevant to the log information. Some of the attribute values can be derived from a map of options standardised by the OCSF schema. One such attribute is Activity ID. Depending on the type of activity performed on the file, you can assign a value from the pre-defined set of values in the schema such as 0 if the event activity is unknown, 1 if a file was created, 2 if a file was read, and so on. You can find more information on standard attribute maps in File System Activity, System Activity Category.

File system activity mapping example

The following is a sample file creation event reported by Sysmon:

File created:
RuleName: technique_id=T1574.010,technique_name=Services File Permissions Weakness
UtcTime: 2023-10-03 23:50:22.438
ProcessGuid: {78c8aea6-5a34-651b-1900-000000005f01}
ProcessId: 1128
Image: C:\Windows\System32\svchost.exe
TargetFilename: C:\Windows\ServiceState\EventLog\Data\lastalive1.dat
CreationUtcTime: 2023-10-03 00:04:00.984
User: NT AUTHORITY\LOCAL SERVICE

When the event is streamed to the Kinesis Data Streams stream, the Kinesis Agent can be used to enrich the event. We’re enriching the event with source_instance_id using ObjectDecoration configured in the agent configuration file.

Because the transformation Lambda function reads from a Kinesis Data Stream, we use the event information from the stream to map the attributes of the File System Activity class. The following mapping table has attributes mapped to the values based on OCSF requirements, the values enclosed in brackets (<>) will come from the event. In the solution implementation section for this pattern, you learn about the transformation Lambda function and mapping implementation for a sample set of events.

OCSF Raw
category_uid 1
category_name System Activity
class_uid 1001
class_name File System Activity
time <UtcTime>
activity_id 1
actor {process: {name: <Image>}}
device {type_id: 6}
unmapped {pid: <ProcessId>, uid: <ProcessGuid>, name: <Image>, user: <User>, rulename: <RuleName>}
file {name: <TargetFilename>, type_id: ‘1’}
type_uid 100101

Table 3: File System Activity class mapping with raw log data

Solution implementation

The solution implementation is published in the AWS Samples GitHub repository titled amazon-security-lake-transformation-library in the windows-sysmon instructions. You will use the repository to deploy the solution in your AWS account.

First update the mapping configuration, then add the custom source in Security Lake and deploy and configure the log streaming and transformation infrastructure, which includes the Kinesis Data Stream, transformation Lambda function and associated IAM roles.

Step 1: Update mapping configuration

Each supported custom source documentation contains the mapping configuration. Update the mapping configuration for the windows-sysmon custom source for the transformation function.

You can find the mapping configuration in the custom source instructions in the amazon-security-lake-transformation-library repository.

Step 2: Add a custom source in Security Lake

As of this writing, Security Lake natively supports AWS CloudTrail, Amazon Route 53 DNS logs, AWS Security Hub findings, Amazon Elastic Kubernetes Service (Amazon EKS) Audit Logs, Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, and AWS Web Application Firewall (AWS WAF). For other log sources that you want to bring into Security Lake, you must configure the custom sources. For the Sysmon logs, you will create a custom source using the Security Lake API. We recommend using dashes in custom source names as opposed to underscores to be able to configure granular access control for S3 objects.

  1. To add the custom source for Sysmon events, configure an IAM role for the AWS Glue crawler that will be associated with the custom source to update the schema in the Security Lake AWS Glue database. You can deploy the ASLCustomSourceGlueRole.yaml CloudFormation template to automate the creation of the IAM role associated with the custom source AWS Glue crawler.
  2. Capture the Amazon Resource Name (ARN) for the IAM role, which is configured as an output of the infrastructure deployed in the previous step.
  3. Add a custom source using the following AWS CLI command. Make sure you replace the <AWS_ACCOUNT_ID>, <SECURITY_LAKE_REGION> and the <GLUE_IAM_ROLE_ARN> placeholders with the AWS account ID you’re deploying into, the Security Lake deployment Region and the ARN of the IAM role created above, respectively. External ID is a unique identifier that is used to establish trust with the AWS identity. You can use External ID to add conditional access from third-party sources and to subscribers.
    aws securitylake create-custom-log-source \
       --source-name windows-sysmon \
       --configuration crawlerConfiguration={"roleArn=<GLUE_IAM_ROLE_ARN>"},providerIdentity={"externalId=CustomSourceExternalId123,principal=<AWS_ACCOUNT_ID>"} \
       --event-classes FILE_ACTIVITY PROCESS_ACTIVITY \
       --region <SECURITY_LAKE_REGION>

    Note: When creating the custom log source, you only need to specify FILE_ACTIVITY and PROCESS_ACTIVITY event classes as these are the only classes mapped in the example configuration deployed in Step 1. If you extend your mapping configuration to handle additional classes, you would add them here.

Step 3: Deploy the transformation infrastructure

The solution uses the AWS SAM framework—an open source framework for building serverless applications—to deploy the OCSF transformation infrastructure. The infrastructure includes a transformation Lambda function, Kinesis data stream, IAM roles for the Lambda function and the hosts running the Kinesis Agent, and encryption keys for the Kinesis data stream. The Lambda function is configured to read events streamed into the Kinesis Data Stream and transform the data into OCSF based on the mapping configuration file. The transformed events are then written to an S3 bucket managed by Security Lake. A sample of the configuration file is provided in the solution repository capturing a subset of the events. You can extend the same for the remaining Sysmon events.

To deploy the infrastructure:

  1. Clone the solution codebase into your choice of integrated development environment (IDE). You can also use AWS CloudShell or AWS Cloud9.
  2. Sign in to the Security Lake delegated administrator account.
  3. Review the prerequisites and detailed deployment steps in the project’s README file. Use the SAM CLI to build and deploy the streaming infrastructure by running the following commands:
    sam build
    
    sam deploy –guided

Step 4: Update the default AWS Glue crawler

Sysmon logs are a complex use case because a single source of logs contains events mapped to multiple schemas. The transformation library handles this by writing each schema to different prefixes (folders) within the target Security Lake bucket. The AWS Glue crawler deployed by Security Lake for the custom log source must be updated to handle prefixes that contain differing schemas.

To update the default AWS Glue crawler:

  1. In the Security Lake delegated administrator account, navigate to the AWS Glue console.
  2. Navigate to Crawlers in the Data Catalog section. Search for the crawler associated with the custom source. It will have the same name as the custom source name. For example, windows-sysmon. Select the check box next to the crawler name, then choose Action and select Edit Crawler.

    Figure 2: Select and edit an AWS Glue crawler

    Figure 2: Select and edit an AWS Glue crawler

  3. Select Edit for the Step 2: Choose data sources and classifiers section on the Review and update page.
  4. In the Choose data sources and classifiers section, make the following changes:
    • For Is your data already mapped to Glue tables?, change the selection to Not yet.
    • For Data sources, select Add a data source. In the selection prompt, select the Security Lake S3 bucket location as presented in the output of the create-custom-source command above. For example, s3://aws-security-data-lake-<region>–<exampleid>/ext/windows-sysmon/. Make sure you include the path all the way to the custom source name and replace the <region> and <exampleid> placeholders with the actual values. Then choose Add S3 data source.
    • Choose Next.
    • On the Configure security settings page, leave everything as is and choose Next.
    • On the Set output and scheduling page, select the Target database as the Security Lake Glue database.
    • In a separate tab, navigate to AWS Glue > Tables. Copy the name of the custom source table created by Security Lake.
    • Navigate back to the AWS Glue crawler configuration tab, update the Table name prefix with the copied table name and add an underscore (_) at the end. For example, amazon_security_lake_table_ap_southeast_2_ext_windows_sysmon_.
    • Under Advanced options, select the checkbox for Create a single schema for each S3 path and for Table level enter 4.
    • Make sure you allow the crawler to enforce table schema to the partitions by selecting the Update all new and existing partitions with metadata from the table checkbox.
    • For the Crawler schedule section, select Monthly from the Frequency dropdown. For Minute, enter 0. This configuration will run the crawler every month.
    • Choose Next, then Update.
Figure 3: Set AWS Glue crawler output and scheduling

Figure 3: Set AWS Glue crawler output and scheduling

To configure hosts to stream log information:

As discussed in the Solution overview section, you use Kinesis Data Streams with a Lambda function to stream Sysmon logs and transform the information into OCSF.

  1. Install Kinesis Agent for Microsoft Windows. There are three ways to install Kinesis Agent on Windows Operating Systems. Using AWS Systems Manager helps automate the deployment and upgrade process. You can also install Kinesis Agent by using a Windows installer package or PowerShell scripts.
  2. After installation you must configure Kinesis Agent to stream log data to Kinesis Data Streams (you can use the following code for this). Kinesis Agent for Windows helps capture important metadata of the host system and enrich information streamed to the Kinesis Data Stream. The Kinesis Agent configuration file is located at %PROGRAMFILES%\Amazon\AWSKinesisTap\appsettings.json and includes three parts—sources, pipes, and sinks:
    • Sources are plugins that gather telemetry.
    • Sinks stream telemetry information to different AWS services, including but not limited to Amazon Kinesis.
    • Pipes connect a source to a sink.
    {
      "Sources": [
        {
          "Id": "Sysmon",
          "SourceType": "WindowsEventLogSource",
          "LogName": "Microsoft-Windows-Sysmon/Operational"
        }
      ],
      "Sinks": [
        {
          "Id": "SysmonLogStream",
          "SinkType": "KinesisStream",
          "StreamName": "<LogCollectionStreamName>",
          "ObjectDecoration": "source_instance_id={ec2:instance-id};",
          "Format": "json",
          "RoleARN": "<KinesisAgentIAMRoleARN>"
        }
      ],
      "Pipes": [
        {
           "Id": "JsonLogSourceToKinesisLogStream",
           "SourceRef": "Sysmon",
           "SinkRef": "SysmonLogStream"
        }
      ],
      "SelfUpdate": 0,
      "Telemetrics": { "off": "true" }
    }

    The preceding configuration shows the information flow through sources, pipes, and sinks using the Kinesis Agent for Windows. Use the sample configuration file provided in the solution repository. Observe the ObjectDecoration key in the Sink configuration; you can use this key to add key information to identify the generating system. For example, to identify whether the event is being generated by an Amazon Elastic Compute Cloud (Amazon EC2) instance or a hybrid server. This information can be used to map the Device attribute in the various OCSF classes such as File System Activity and Process Activity. The <KinesisAgentIAMRoleARN> is configured by the transformation library deployment unless you create your own IAM role and provide it as a parameter to the deployment.

    Update the Kinesis agent configuration file %PROGRAMFILES%\Amazon\AWSKinesisTap\appsettings.json with the contents of the kinesis_agent_configuration.json file from this repository. Make sure you replace the <LogCollectionStreamName> and <KinesisAgentIAMRoleARN> placeholders with the value of the CloudFormation outputs, LogCollectionStreamName and KinesisAgentIAMRoleARN, that you captured in the Deploy transformation infrastructure step.

  3. Start Kinesis Agent on the hosts to start streaming the logs to Security Lake buckets. Open an elevated PowerShell command prompt window, and start Kinesis Agent for Windows using the following PowerShell command:
    Start-Service -Name AWSKinesisTap

Pattern 2: Log collection from services and products using AWS Glue

You can use Amazon VPC to launch resources in an isolated network. AWS Network Firewall provides the capability to filter network traffic at the perimeter of your VPCs and define stateful rules to configure fine-grained control over network flow. Common Network Firewall use cases include intrusion detection and protection, Transport Layer Security (TLS) inspection, and egress filtering. Network Firewall supports multiple destinations for log delivery, including Amazon S3.

In this pattern, you focus on adding a custom source in Security Lake where the product in use delivers raw logs to an S3 bucket.

Solution overview

This solution uses an S3 bucket (the staging bucket) for raw log storage using the prerequisites defined earlier in this post. Use AWS Glue to configure the ETL and load the OCSF transformed logs into the Security Lake S3 bucket.

Figure 4: Architecture using AWS Glue for ETL

Figure 4: Architecture using AWS Glue for ETL

Figure 4 shows the architecture for this pattern. This pattern applies to AWS services or partner services that natively support log storage in S3 buckets. The solution starts by defining the OCSF mapping.

Mapping

Network firewall records two types of log information—alert logs and netflow logs. Alert logs report traffic that matches the stateful rules configured in your environment. Flow logs are network traffic flow logs that capture network traffic information for standard stateless rule groups. You can use stateful rules for use cases such as egress filtering to restrict the external domains that the resources deployed in a VPC in your AWS account have access to. In the Network Firewall use case, events can be mapped to various attributes in the Network Activity class in the Network Activity category.

Network firewall sample event: netflow log

{
    "firewall_name":"firewall",
    "availability_zone":"us-east-1b",
    "event_timestamp":"1601587565",
    "event":{
        "timestamp":"2020-10-01T21:26:05.007515+0000",
        "flow_id":1770453319291727,
        "event_type":"netflow",
        "src_ip":"45.129.33.153",
        "src_port":47047,
        "dest_ip":"172.31.16.139",
        "dest_port":16463,
        "proto":"TCP",
        "netflow":{
            "pkts":1,
            "bytes":60,
            "start":"2020-10-01T21:25:04.070479+0000",
            "end":"2020-10-01T21:25:04.070479+0000",
            "age":0,
            "min_ttl":241,
            "max_ttl":241
        },
        "tcp":{
            "tcp_flags":"02",
            "syn":true
        }
    }
}

Network firewall sample event: alert log

{
    "firewall_name":"firewall",
    "availability_zone":"zone",
    "event_timestamp":"1601074865",
    "event":{
        "timestamp":"2020-09-25T23:01:05.598481+0000",
        "flow_id":1111111111111111,
        "event_type":"alert",
        "src_ip":"10.16.197.56",
        "src_port":49157,
        "dest_ip":"10.16.197.55",
        "dest_port":8883,
        "proto":"TCP",
        "alert":{
            "action":"allowed",
            "signature_id":2,
            "rev":0,
            "signature":"",
            "category":"",
            "severity":3
        }
    }
}

The target mapping for the preceding alert logs is as follows:

Mapping for alert logs

OCSF Raw
app_name <firewall_name>
activity_id 6
activity_name Traffic
category_uid 4
category_name Network activity
class_uid 4001
type_uid 400106
class_name Network activity
dst_endpoint {ip: <event.dest_ip>, port: <event.dest_port>}
src_endpoint {ip: <event.src_ip>, port: <event.src_port>}
time <event.timestamp>
severity_id <event.alert.severity>
connection_info {uid: <event.flow_id>, protocol_name: <event.proto>}
cloud.provider AWS
metadata.profiles [cloud, firewall]
metadata.product.name AWS Network Firewall
metadata.product.feature.name Firewall
metadata.product.vendor_name AWS
severity High
unmapped {alert: {action: <event.alert.action>, signature_id: <event.alert.signature_id>, rev: <event.alert.rev>, signature: <event.alert.signature>, category: <event.alert.category>, tls_inspected: <event.alert.tls_inspected>}}

Mapping for netflow logs

OCSF Raw
app_name <firewall_name>
activity_id 6
activity_name Traffic
category_uid 4
category_name Network activity
class_uid 4001
type_uid 400106
class_name Network activity
dst_endpoint {ip: <event.dest_ip>, port: <event.dest_port>}
src_endpoint {ip: <event.src_ip>, port: <event.src_port>}
Time <event.timestamp>
connection_info {uid: <event.flow_id>, protocol_name: <event.proto>, tcp_flags: <event.tcp.tcp_flags>}
cloud.provider AWS
metadata.profiles [cloud, firewall]
metadata.product.name AWS Network Firewall
metadata.product.feature.name Firewall
metadata.product.vendor_name AWS
severity Informational
severity_id 1
start_time <event.netflow.start>
end_time <event.netflow.end>
Traffic {bytes: <event.netflow.bytes>, packets: <event.netflow.packets>}
Unmapped {availability_zone: <availability_zone>, event_type: <event.event_type>, netflow: {age: <event.netflow.age>, min_ttl: <event.netflow.min_ttl>, max_ttl: <event.netflow.max_ttl>}, tcp: {syn: <event.tcp.syn>, fin: <event.tcp.fin>, ack: <event.tcp.ack>, psh: <event.tcp.psh>}}

Solution implementation

The solution implementation is published in the AWS Samples GitHub repository titled amazon-security-lake-transformation-library in the Network Firewall instructions. Use the repository to deploy this pattern in your AWS account. The solution deployment is a four-step process:

  1. Update the mapping configuration
  2. Configure the log source to use Amazon S3 for log delivery
  3. Add a custom source in Security Lake
  4. Deploy the log staging and transformation infrastructure

Because Network Firewall logs can be mapped to a single OCSF class, you don’t need to update the AWS Glue crawler as in the previous pattern. However, you must update the AWS Glue crawler if you want to add a custom source with multiple OCSF classes.

Step 1: Update the mapping configuration

Each supported custom source documentation contains the mapping configuration. Update the mapping configuration for the Network Firewall custom source for the transformation function.

The mapping configuration can be found in the custom source instructions in the amazon-security-lake-transformation-library repository

Step 2: Configure the log source to use S3 for log delivery

Configure Network Firewall to log to Amazon S3. The transformation function infrastructure deploys a staging S3 bucket for raw log storage. If you already have an S3 bucket configured for raw log delivery, you can update the value of the parameter RawLogS3BucketName during deployment. The deployment configures event notifications with Amazon Simple Queue Service (Amazon SQS). The transformation Lambda function is invoked by SQS event notifications when Network Firewall delivers log files in the staging S3 bucket.

Step 3: Add a custom source in Security Lake

As with the previous pattern, add a custom source for Network Firewall in Security Lake. In the previous pattern you used the AWS CLI to create and configure the custom source. In this pattern, we take you through the steps to do the same using the AWS console.

To add a custom source:

  1. Open the Security Lake console
  2. In the navigation pane, select Custom sources.
  3. Then select Create custom source.

    Figure 5: Create a custom source

    Figure 5: Create a custom source

  4. Under Custom source details enter a name for the custom log source such as network_firewall and choose Network Activity as the OCSF Event class

    Figure 6: Data source name and OCSF Event class

    Figure 6: Data source name and OCSF Event class

  5. Under Account details, enter your AWS account ID for the AWS account ID and External ID fields. Leave Create and use a new service role selected and choose Create.

    Figure 7: Account details and service access

    Figure 7: Account details and service access

  6. The custom log source will now be available.

Step 4: Deploy transformation infrastructure

As with the previous pattern, use AWS SAM CLI to deploy the transformation infrastructure.

To deploy the transformation infrastructure:

  1. Clone the solution codebase into your choice of IDE.
  2. Sign in to the Security Lake delegated administrator account.
  3. The infrastructure is deployed using the AWS SAM, which is an open source framework for building serverless applications. Review the prerequisites and detailed deployment steps in the project’s README file. Use the SAM CLI to build and deploy the streaming infrastructure by running the following commands:
    sam build
    
    sam deploy --guided

Clean up

The resources created in the previous patterns can be cleaned up by running the following command:

sam delete

You also need to manually delete the custom source by following the instructions from the Security Lake User Guide.

Pattern 3: Log collection using integration with supported AWS services.

In a threat hunting and response use case, customers often use multiple sources of logs to correlate information to find more information on unauthorized third-party interactions originating from trusted software vendors. These interactions can be due to vulnerable components in the product or exposed credentials such as integration API keys. An operationally effective way to source logs from partner software and external vendors is to use the supported AWS services that natively integrate with Security Lake.

AWS Security Hub

AWS Security Hub is a cloud security posture measurement service that provides a comprehensive view of the security posture of your AWS environment. Security Hub supports integration with several AWS services including AWS Systems Manager Patch Manager, Amazon Macie, Amazon GuardDuty, and Amazon Inspector. For the full list, see AWS service integrations with AWS Security Hub. Security Hub also integrates with multiple third-party partner products that you can use. These products support sending findings to Security Hub seamlessly.

Security Lake natively supports ingestion of Security Hub findings, which centralizes the findings from the source integrations into Security Lake. Before you start building a custom source, we recommend you review whether the product is supported by Security Hub, which could remove the need for building manual mapping and transformation solutions.

AWS AppFabric

AWS AppFabric is a fully managed software as a service (SaaS) interoperability solution. Security Lake supports AppFabric output schema and format—OCSF and JSON respectively. Security Lake supports AppFabric as a custom source using Amazon Kinesis Data Firehose delivery stream. You can find step-by-step instructions in the AppFabric user guide.

Conclusion

Security Lake offers customers the capability to centralize disparate log sources in a single format, OCSF. Using OCSF improves correlation and enrichment activities because security teams no longer have to build queries based on the individual log source schema. Log data is normalized such that customers can use the same schema across the log data collected. Using the patterns and solution identified in this post, you can significantly reduce the effort involved in building custom sources to bring your own data into Security Lake.

You can extend the concepts and mapping function code provided in the amazon-security-lake-transformation-library to build out a log ingestion and ETL solution. You can use the flexibility offered by Security Lake and the custom source feature to ingest log data generated by all sources including third-party tools, log forwarding software, AWS services, and hybrid solutions.

In this post, we provided you with three patterns that you can use across multiple log sources. The most flexible being Pattern 1, where you can choose the OCSF mapped class and attributes that are in-line with your organizational mappings and custom source configuration with Security Lake. You can continue to use the mapping function code from the amazon-security-lake-transformation-library demonstrated through this post and update the mapping variable for the OCSF class you’re mapping to. This solution can be scaled to build a range of custom sources to enhance your threat detection and investigation workflow.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Pratima Singh

Pratima Singh
Pratima is a Security Specialist Solutions Architect with Amazon Web Services based out of Sydney, Australia. She is a security enthusiast who enjoys helping customers find innovative solutions to complex business challenges. Outside of work, Pratima enjoys going on long drives and spending time with her family at the beach.

Chris Lamont-Smith

Chris Lamont-Smith
Chris is a Senior Security Consultant working in the Security, Risk, and Compliance team for AWS ProServe based out of Perth, Australia. He enjoys working in the area where security and data analytics intersect and is passionate about helping customers gain actionable insights from their security data. When Chris isn’t working, he is out camping or off-roading with his family in the Australian bush.

Improve your Amazon OpenSearch Service performance with OpenSearch Optimized Instances

Post Syndicated from Jatinder Singh original https://aws.amazon.com/blogs/big-data/improve-your-amazon-opensearch-service-performance-with-opensearch-optimized-instances/

Amazon OpenSearch Service introduced the OpenSearch Optimized Instances (OR1), deliver price-performance improvement over existing instances. The newly introduced OR1 instances are ideally tailored for heavy indexing use cases like log analytics and observability workloads.

OR1 instances use a local and a remote store. The local storage utilizes either Amazon Elastic Block Store (Amazon EBS) of type gp3 or io1 volumes, and the remote storage uses Amazon Simple Storage Service (Amazon S3). For more details about OR1 instances, refer to Amazon OpenSearch Service Under the Hood: OpenSearch Optimized Instances (OR1).

In this post, we conduct experiments using OpenSearch Benchmark to demonstrate how the OR1 instance family improves indexing throughput and overall domain performance.

Getting started with OpenSearch Benchmark

OpenSearch Benchmark, a tool provided by the OpenSearch Project, comprehensively gathers performance metrics from OpenSearch clusters, including indexing throughput and search latency. Whether you’re tracking overall cluster performance, informing upgrade decisions, or assessing the impact of workflow changes, this utility proves invaluable.

In this post, we compare the performance of two clusters: one powered by memory-optimized instances and the other by OR1 instances. The dataset comprises HTTP server logs from the 1998 World Cup website. With the OpenSearch Benchmark tool, we conduct experiments to assess various performance metrics, such as indexing throughput, search latency, and overall cluster efficiency. Our aim is to determine the most suitable configuration for our specific workload requirements.

You can install OpenSearch Benchmark directly on a host running Linux or macOS, or you can run OpenSearch Benchmark in a Docker container on any compatible host.

OpenSearch Benchmark includes a set of workloads that you can use to benchmark your cluster performance. Workloads contain descriptions of one or more benchmarking scenarios that use a specific document corpus to perform a benchmark against your cluster. The document corpus contains indexes, data files, and operations invoked when the workflow runs.

When assessing your cluster’s performance, it is recommended to use a workload similar to your cluster’s use cases, which can save you time and effort. Consider the following criteria to determine the best workload for benchmarking your cluster:

  • Use case – Selecting a workload that mirrors your cluster’s real-world use case is essential for accurate benchmarking. By simulating heavy search or indexing tasks typical for your cluster, you can pinpoint performance issues and optimize settings effectively. This approach makes sure benchmarking results closely match actual performance expectations, leading to more reliable optimization decisions tailored to your specific workload needs.
  • Data – Use a data structure similar to that of your production workloads. OpenSearch Benchmark provides examples of documents within each workload to understand the mapping and compare with your own data mapping and structure. Every benchmark workload is composed of the following directories and files for you to compare data types and index mappings.
  • Query types – Understanding your query pattern is crucial for detecting the most frequent search query types within your cluster. Employing a similar query pattern for your benchmarking experiments is essential.

Solution overview

The following diagram explains how OpenSearch Benchmark connects to your OpenSearch domain to run workload benchmarks.Scope of solution

The workflow comprises the following steps:

  1. The first step involves running OpenSearch Benchmark using a specific workload from the workloads repository. The invoke operation collects data about the performance of your OpenSearch cluster according to the selected workload.
  2. OpenSearch Benchmark ingests the workload dataset into your OpenSearch Service domain.
  3. OpenSearch Benchmark runs a set of predefined test procedures to capture OpenSearch Service performance metrics.
  4. When the workload is complete, OpenSearch Benchmark outputs all related metrics to measure the workload performance. Metric records are by default stored in memory, or you can set up an OpenSearch Service domain to store the generated metrics and compare multiple workload executions.

In this post, we used the http_logs workload to conduct performance benchmarking. The dataset comprises 247 million documents designed for ingestion and offers a set of sample queries for benchmarking. Follow the steps outlined in the OpenSearch Benchmark User Guide to deploy OpenSearch Benchmark and run the http_logs workload.

Prerequisites

You should have the following prerequisites:

In this post, we deployed OpenSearch Benchmark in an AWS Cloud9 host using an Amazon Linux 2 instance type m6i.2xlarge with a capacity of 8 vCPUs, 32 GiB memory, and 512 TiB storage.

Performance analysis using the OR1 instance type in OpenSearch Service

In this post, we conducted a performance comparison between two different configurations of OpenSearch Service:

  • Configuration 1 – Cluster manager nodes and three data nodes of memory-optimized r6g.large instances
  • Configuration 2 – Cluster manager nodes and three data nodes of or1.larges instances

In both configurations, we use the same number and type of cluster manager nodes: three c6g.xlarge.

You can set up different configurations with the supported instance types in OpenSearch Service to run performance benchmarks.

The following table summarizes our OpenSearch Service configuration details.

  Configuration 1 Configuration 2
Number of cluster manager nodes 3 3
Type of cluster manager nodes c6g.xlarge c6g.xlarge
Number of data nodes 3 3
Type of data node r6g.large or1.large
Data node: EBS volume size (GP3) 200 GB 200 GB
Multi-AZ with standby enabled Yes Yes

Now let’s examine the performance details between the two configurations.

Performance benchmark comparison

The http_logs dataset contains HTTP server logs from the 1998 World Cup website between April 30, 1998 and July 26, 1998. Each request consists of a timestamp field, client ID, object ID, size of the request, method, status, and more. The uncompressed size of the dataset is 31.1 GB with 247 million JSON documents. The amount of load sent to both domain configurations is identical. The following table displays the amount of time taken to run various aspects of an OpenSearch workload on our two configurations.

Category Metric Name

Configuration 1

(3* r6g.large data nodes)

Runtimes

Configuration 2

(3* or1.large data nodes)

Runtimes

Performance Difference
Indexing Cumulative indexing time of primary shards 207.93 min 142.50 min 31%
Indexing Cumulative flush time of primary shards 21.17 min 2.31 min 89%
Garbage Collection Total Young Gen GC time 43.14 sec 24.57 sec 43%
bulk-index-append p99 latency 10857.2 ms 2455.12 ms 77%
query-Mean Throughput 29.76 ops/sec 36.24 ops/sec 22%
query-match_all(default) p99 latency 40.75 ms 32.99 ms 19%
query-term p99 latency 7675.54 ms 4183.19 ms 45%
query-range p99 latency 59.5316 ms 51.2864 ms 14%
query-hourly_aggregation p99 latency 5308.46 ms 2985.18 ms 44%
query-multi_term_aggregation p99 latency 8506.4 ms 4264.44 ms 50%

The benchmarks show a notable enhancement across various performance metrics. Specifically, OR1.large data nodes demonstrate a 31% reduction in indexing time for primary shards compared to r6g.large data nodes. OR1.large data nodes also exhibit a 43% improvement in garbage collection efficiency and significant enhancements in query performance, including term, range, and aggregation queries.

The extent of improvement depends on the workload. Therefore, make sure to run custom workloads as expected in your production environments in terms of indexing throughput, type of search queries, and concurrent requests.

Migration journey to OR1

The OR1 instance family is available in OpenSearch Service 2.11 or higher. Usually, if you’re using OpenSearch Service and you want to benefit from new released features in a specific version, you would follow the supported upgrade paths to upgrade your domain.

However, to use the OR1 instance type, you need to create a new domain with OR1 instances and then migrate your existing domain to the new domain. The migration journey to OpenSearch Service domain using an OR1 instance is similar to a typical OpenSearch Service migration scenario. Critical aspects involve determining the appropriate size for the target environment, selecting suitable data migration methods, and devising a seamless cutover strategy. These elements provide optimal performance, smooth data transition, and minimal disruption throughout the migration process.

To migrate data to a new OR1 domain, you can use the snapshot restore option or use Amazon OpenSearch Ingestion to migrate the data for your source.

For instructions on migration, refer to Migrating to Amazon OpenSearch Service.

Clean up

To avoid incurring continued AWS usage charges, make sure you delete all the resources you created as part of this post, including your OpenSearch Service domain.

Conclusion

In this post, we ran a benchmark to review the performance of the OR1 instance family compared to the memory-optimized r6g instance. We used OpenSearch Benchmark, a comprehensive tool for gathering performance metrics from OpenSearch clusters.

Learn more about how OR1 instances work and experiment with OpenSearch Benchmark to make sure your OpenSearch Service configuration matches your workload demand.


About the Authors

Jatinder Singh is a Senior Technical Account Manager at AWS and finds satisfaction in aiding customers in their cloud migration and innovation endeavors. Beyond his professional life, he relishes spending moments with his family and indulging in hobbies such as reading, culinary pursuits, and playing chess.

Hajer Bouafif is an Analytics Specialist Solutions Architect at Amazon Web Services. She focuses on Amazon OpenSearch Service and helps customers design and build well-architected analytics workloads in diverse industries. Hajer enjoys spending time outdoors and discovering new cultures.

Puneetha Kumara is a Senior Technical Account Manager at AWS, with over 15 years of industry experience, including roles in cloud architecture, systems engineering, and container orchestration.

Manpreet Kour is a Senior Technical Account Manager at AWS and is dedicated to ensuring customer satisfaction. Her approach involves a deep understanding of customer objectives, aligning them with software capabilities, and effectively driving customer success. Outside of her professional endeavors, she enjoys traveling and spending quality time with her family.

Centrally manage VPC network ACL rules to block unwanted traffic using AWS Firewall Manager

Post Syndicated from Bryan Van Hook original https://aws.amazon.com/blogs/security/centrally-manage-vpc-network-acl-rules-to-block-unwanted-traffic-using-aws-firewall-manager/

Amazon Virtual Private Cloud (Amazon VPC) provides two options for controlling network traffic: network access control lists (ACLs) and security groups. A network ACL defines inbound and outbound rules that allow or deny traffic based on protocol, IP address range, and port range. Security groups determine which inbound and outbound traffic is allowed on a network interface, but they cannot explicitly deny traffic like a network ACL can. Every VPC subnet is associated with a network ACL that ultimately determines which traffic can enter or leave the subnet, even if a security group allows it. Network ACLs provide a layer of network controls that augment your security groups.

There are situations when you might want to deny specific sources or destinations within the range of network traffic allowed by security groups. For example, you want to deny inbound traffic from malicious sources on the internet, or you want to deny outbound traffic to ports or protocols used by exploits or malware. Security group rules can only control what traffic is allowed. If you want to deny specific traffic within the range of allowed traffic from security groups, you need to use network ACL rules. If you want to deny specific types of traffic in many VPCs, you need to update each network ACL associated with subnets in each of those VPCs. We heard from customers that implementing a baseline of common network ACL rules can be challenging to manage across many Amazon Web Services (AWS) accounts, so we expanded AWS Firewall Manager capabilities to make this easier.

AWS Firewall Manager network ACL security policies allow you to centrally manage network ACL rules for VPC subnets across AWS accounts in your organization. The following sections demonstrate how you can use network ACL policies to manage common network ACL rules that deny inbound and outbound traffic.

Deny inbound traffic using a network ACL security policy

If you have not already set up a Firewall Manager administrator account, see Firewall Manager prerequisites. Note that network ACL policies require your AWS Config configuration recorder to include the AWS::EC2::NetworkAcl and AWS::EC2::Subnet resource types.

Let’s review an example of how you can now use Firewall Manager to centrally manage a network ACL rule that denies inbound traffic from a public source IP range.

To deny inbound traffic:

  1. Sign in to your Firewall Manager delegated administrator account, open the AWS Management Console, and go to Firewall Manager.
  2. In the navigation pane, under AWS Firewall Manager, select Security policies.
  3. On the Filter menu, select the AWS Region where your VPC subnets are defined, and choose Create policy. In this example, we select US East (N. Virginia).
  4. Under Policy details, select Network ACL, and then choose Next.

    Figure 1: Network ACL policy type and Region

    Figure 1: Network ACL policy type and Region

  5. On Policy name, enter a Policy name and Policy description.

    Figure 2: Network ACL policy name and description

    Figure 2: Network ACL policy name and description

  6. In the Network ACL policy rules section, select the Inbound rules tab.
  7. In the First rules section, choose Add rules.

    Figure 3: Add rules in the First rules section

    Figure 3: Add rules in the First rules section

  8. In the Inbound rules window, choose Add inbound rules.

    Figure 4: Add inbound rules

    Figure 4: Add inbound rules

  9. For Inbound rules, choose the following:
    1. For Type, select All traffic.
    2. For Protocol, select All.
    3. For Port range, select All.
    4. For Source, enter an IP address range that you want to deny. In this example, we use 192.0.2.0/24.
    5. For Action, select Deny.
    6. Choose Add Rules.

    Figure 5: Configure a network ACL inbound rule

    Figure 5: Configure a network ACL inbound rule

  10. In Network ACL policy rules, under First rules, review the deny rule.

    Figure 6: Review the inbound deny rule

    Figure 6: Review the inbound deny rule

  11. Under Policy action, select the following:
    1. Select Auto remediate any noncompliant resources.
    2. Under Force Remediation, select Force remediate first rules. Firewall Manager compares your existing network ACL rules with rules defined in the policy. A conflict exists if a policy rule has the opposite action of an existing rule and overlaps with the existing rule’s protocol, address range, or port range. In these cases, Firewall Manager will not remediate the network ACL unless you enable force remediation.

    Figure 7: Configure the policy action

    Figure 7: Configure the policy action

  12. Choose Next.
  13. Policy scope, select the following:
    1. Under AWS accounts this policy applies to, select the scope of accounts that apply. In this example, we include all accounts.
    2. Under Resource type, select Subnet.
    3. Under Resources, select the scope of resources that apply. In this example, we only include subnets that have a particular tag.

    Figure 8: Configure the policy scope

    Figure 8: Configure the policy scope

  14. Enable resource cleanup if you want Firewall Manager to remove the rules it added to network ACLs associated with subnets that are no longer in scope. To enable cleanup, select Automatically remove protections from resources that leave the policy scope, and choose Next.

    Figure 9: Enable resource cleanup

    Figure 9: Enable resource cleanup

  15. Under Configure policy tags, define the tags you want to associate with your policy, and then choose Next.
  16. Under Review and create policy, choose Next.

Before creating the Firewall Manager policy, the subnet is associated with a default network ACL, as shown in Figure 10.

Figure 10: Default network ACL rules before the subnet is in scope

Figure 10: Default network ACL rules before the subnet is in scope

As shown in Figure 11, the subnet is now associated with a network ACL managed by Firewall Manager. The original Allow rule has been preserved and moved to priority 5,000. The Deny rule has been added with priority 1.

Figure 11: Inbound rules in network ACL managed by Firewall Manager

Figure 11: Inbound rules in network ACL managed by Firewall Manager

Deny outbound traffic using a network ACL security policy

You can also use Firewall Manager to implement outbound network ACL rules to deny the use of ports used by malware or software vulnerabilities. In this example, we’re blocking the use of LDAP port 389.

  1. Sign in to your Firewall Manager delegated administrator account and open the Firewall Manager console.
  2. In the navigation pane, under AWS Firewall Manager, select Security policies.
  3. On the Filter menu, select the AWS Region where your VPC subnets are defined, and choose Create policy. In this example, we select US East (N. Virginia).
  4. Under Policy details, select Network ACL, and then choose Next.
  5. Enter a Policy name and Policy description.
  6. In the Network ACL policy rules section, select the Outbound rules tab.
  7. In the First rules section, choose Add rules.

    Figure 12: Add rules in the First rules section

    Figure 12: Add rules in the First rules section

  8. Under Outbound rules, choose Add outbound rules.
  9. In Outbound rules, select the following:
    1. For Type, select LDAP (389).
    2. For Destination, enter 0.0.0.0/0.
    3. For Action, select Deny.
    4. Choose Add Rules.

    Figure 13: Configure a network ACL outbound rule

    Figure 13: Configure a network ACL outbound rule

  10. On the Network ACL policy rules page, under First rules, review the deny rule.

    Figure 14: Review the outbound deny rule

    Figure 14: Review the outbound deny rule

  11. In Policy action, under Policy action, select the following:
    1. Select Auto remediate any noncompliant resources.
    2. Under Force Remediation, select Force remediate first rules, and then choose Next.

    Figure 15: Configure the policy action

    Figure 15: Configure the policy action

  12. Under Policy scope, choose the following:
    1. Under AWS accounts this policy applies to, select the scope of accounts that apply. In this example, we include all accounts by selecting Include all accounts under my organization.
    2. Under Resource type, select Subnet.
    3. Under Resources, select the scope of resources that apply. In this example, we select Include only subnets that all the specified resource tags.

    Figure 16: Configure the policy scope

    Figure 16: Configure the policy scope

  13. On Resource cleanup, enable resource cleanup if you want Firewall Manager to remove rules it added to network ACLs associated with subnets that are no longer in scope. To enable resource cleanup, select Automatically remove protections from resources that leave the policy scope, and then choose Next.

    Figure 17: Enable resource cleanup

    Figure 17: Enable resource cleanup

  14. Under Configure policy tags, define the tags you want to associate with your policy, and then choose Next.
  15. Under Review and create policy, choose Next.

Before creating the Firewall Manager policy, the subnet is associated with a network ACL that already contains rules with priority 100 and 101, as shown in Figure 18.

Figure 18: Rules in original network ACL

Figure 18: Rules in original network ACL

As shown in Figure 19, the subnet is now associated with a network ACL managed by Firewall Manager. The original rules have been preserved and moved to priority 5,000 and 5,100. The Deny rule for LDAP has been added with priority 1.

Figure 19: Outbound rules in network ACL managed by Firewall Manager

Figure 19: Outbound rules in network ACL managed by Firewall Manager

Working with network ACLs managed by Firewall Manager

Firewall Manager network ACL policies allow you to manage up to 5 inbound and 5 outbound rules. Network ACLs can support a total of 20 inbound rules and 20 outbound rules by default. This limit can be increased up to 40 inbound rules and 40 outbound rules, but network performance might be impacted. Consider AWS Network Firewall if you need support for more rules and a broader set of features.

To diagnose overly restrictive network ACL rules, see Querying Amazon VPC flow logs to learn more about using Amazon Athena to analyze your VPC flow logs.

AWS accounts that are in scope of your Firewall Manager policy might have identities with permission to modify network ACLs created by Firewall Manager. You can use a service control policy (SCP) to deny AWS Identity and Access Management (IAM) actions that modify network ACLs if you want to make sure that they are exclusively managed by Firewall Manager. Firewall Manager uses service-linked roles, which are not restricted by SCPs. The following example SCP denies network ACL updates without restricting Firewall Manager:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DenyNaclUpdateExceptFMS",
      "Effect": "Deny",
      "Action": [
        "ec2:CreateNetworkAclEntry",
        "ec2:DeleteNetworkAclEntry",
        "ec2:ReplaceNetworkAclAssociation",
        "ec2:ReplaceNetworkAclEntry"
      ],
      "Resource": "*"
    }
  ]
}

Summary

Prior to AWS Firewall Manager network ACL security policies, you had to implement your own process to orchestrate updates to network ACLs across VPC subnets in your organization in AWS Organizations. AWS Firewall Manager network ACL security policies allow you to centrally define common network ACL rules that are automatically applied to VPC subnets across your organization, even as you add new accounts and resources. In this post, we demonstrated how you can use network ACL policies in a variety of scenarios, such as blocking ingress from malicious sources and blocking egress to destinations used by malware and exploits. You can also use network ACL policies to implement an allow list. For example, you might only want to allow egress to your on-premises network.

To get started, explore network ACL security policies in the Firewall Manager console. For more information, see the AWS Firewall Manager Developer Guide and send feedback to AWS re:Post for AWS Firewall Manager or through your AWS support team.

Bryan Van Hook

Bryan Van Hook
Bryan is a Senior Security Solutions Architect at AWS. He has over 25 years of experience in software engineering, cloud operations, and internet security. He spends most of his time helping customers gain the most value from native AWS security services. Outside of his day job, Bryan can be found playing tabletop games and acoustic guitar.

Author

Jesse Lepich
Jesse is a Senior Security Solutions Architect at AWS based in Lake St. Louis, Missouri, focused on helping customers implement native AWS security services. Outside of cloud security, his interests include relaxing with family, barefoot waterskiing, snowboarding and snow skiing, surfing, boating and sailing, and mountain climbing.

Amazon MWAA best practices for managing Python dependencies

Post Syndicated from Mike Ellis original https://aws.amazon.com/blogs/big-data/amazon-mwaa-best-practices-for-managing-python-dependencies/

Customers with data engineers and data scientists are using Amazon Managed Workflows for Apache Airflow (Amazon MWAA) as a central orchestration platform for running data pipelines and machine learning (ML) workloads. To support these pipelines, they often require additional Python packages, such as Apache Airflow Providers. For example, a pipeline may require the Snowflake provider package for interacting with a Snowflake warehouse, or the Kubernetes provider package for provisioning Kubernetes workloads. As a result, they need to manage these Python dependencies efficiently and reliably, providing compatibility with each other and the base Apache Airflow installation.

Python includes the tool pip to handle package installations. To install a package, you add the name to a special file named requirements.txt. The pip install command instructs pip to read the contents of your requirements file, determine dependencies, and install the packages. Amazon MWAA runs the pip install command using this requirements.txt file during initial environment startup and subsequent updates. For more information, see How it works.

Creating a reproducible and stable requirements file is key for reducing pip installation and DAG errors. Additionally, this defined set of requirements provides consistency across nodes in an Amazon MWAA environment. This is most important during worker auto scaling, where additional worker nodes are provisioned and having different dependencies could lead to inconsistencies and task failures. Additionally, this strategy promotes consistency across different Amazon MWAA environments, such as dev, qa, and prod.

This post describes best practices for managing your requirements file in your Amazon MWAA environment. It defines the steps needed to determine your required packages and package versions, create and verify your requirements.txt file with package versions, and package your dependencies.

Best practices

The following sections describe the best practices for managing Python dependencies.

Specify package versions in the requirements.txt file

When creating a Python requirements.txt file, you can specify just the package name, or the package name and a specific version. Adding a package without version information instructs the pip installer to download and install the latest available version, subject to compatibility with other installed packages and any constraints. The package versions selected during environment creation may be different than the version selected during an auto scaling event later on. This version change can create package conflicts leading to pip install errors. Even if the updated package installs properly, code changes in the package can affect task behavior, leading to inconsistencies in output. To avoid these risks, it’s best practice to add the version number to each package in your requirements.txt file.

Use the constraints file for your Apache Airflow version

A constraints file contains the packages, with versions, verified to be compatible with your Apache Airflow version. This file adds an additional validation layer to prevent package conflicts. Because the constraints file plays such an important role in preventing conflicts, beginning with Apache Airflow v2.7.2 on Amazon MWAA, your requirements file must include a --constraint statement. If a --constraint statement is not supplied, Amazon MWAA will specify a compatible constraints file for you.

Constraint files are available for each Airflow version and Python version combination. The URLs have the following form:

https://raw.githubusercontent.com/apache/airflow/constraints-${AIRFLOW_VERSION}/constraints-${PYTHON_VERSION}.txt

The official Apache Airflow constraints are guidelines, and if your workflows require newer versions of a provider package, you may need to modify your constraints file and include it in your DAG folder. When doing so, the best practices outlined in this post become even more important to guard against package conflicts.

Create a .zip archive of all dependencies

Creating a .zip file containing the packages in your requirements file and specifying this as the package repository source makes sure the exact same wheel files are used during your initial environment setup and subsequent node configurations. The pip installer will use these local files for installation rather than connecting to the external PyPI repository.

Test the requirements.txt file and dependency .zip file

Testing your requirements file before release to production is key to avoiding installation and DAG errors. Testing both locally, with the MWAA local runner, and in a dev or staging Amazon MWAA environment, are best practices before deploying to production. You can use continuous integration and delivery (CI/CD) deployment strategies to perform the requirements and package installation testing, as described in Automating a DAG deployment with Amazon Managed Workflows for Apache Airflow.

Solution overview

This solution uses the MWAA local runner, an open source utility that replicates an Amazon MWAA environment locally. You use the local runner to build and validate your requirements file, and package the dependencies. In this example, you install the snowflake and dbt-cloud provider packages. You then use the MWAA local runner and a constraints file to determine the exact version of each package compatible with Apache Airflow. With this information, you then update the requirements file, pinning each package to a version, and retest the installation. When you have a successful installation, you package your dependencies and test in a non-production Amazon MWAA environment.

We use MWAA local runner v2.8.1 for this walkthrough and walk through the following steps:

  1. Download and build the MWAA local runner.
  2. Create and test a requirements file with package versions.
  3. Package dependencies.
  4. Deploy the requirements file and dependencies to a non-production Amazon MWAA environment.

Prerequisites

For this walkthrough, you should have the following prerequisites:

Set up the MWAA local runner

First, you download the MWAA local runner version matching your target MWAA environment, then you build the image.

Complete the following steps to configure the local runner:

  1. Clone the MWAA local runner repository with the following command:
    git clone [email protected]:aws/aws-mwaa-local-runner.git -b v2.8.1

  2. With Docker running, build the container with the following command:
    cd aws-mwaa-local-runner
     ./mwaa-local-env build-image

Create and test a requirements file with package versions

Building a versioned requirements file makes sure all Amazon MWAA components have the same package versions installed. To determine the compatible versions for each package, you start with a constraints file and an un-versioned requirements file, allowing pip to resolve the dependencies. Then you create your versioned requirements file from pip’s installation output.

The following diagram illustrates this workflow.

Requirements file testing process

To build an initial requirements file, complete the following steps:

  1. In your MWAA local runner directory, open requirements/requirements.txt in your preferred editor.

The default requirements file will look similar to the following:

--constraint "https://raw.githubusercontent.com/apache/airflow/constraints-2.8.1/constraints-3.11.txt"
apache-airflow-providers-snowflake==5.2.1
apache-airflow-providers-mysql==5.5.1
  1. Replace the existing packages with the following package list:
--constraint "https://raw.githubusercontent.com/apache/airflow/constraints-2.8.1/constraints-3.11.txt"
apache-airflow-providers-snowflake
apache-airflow-providers-dbt-cloud[http]
  1. Save requirements.txt.
  2. In a terminal, run the following command to generate the pip install output:
./mwaa-local-env test-requirements

test-requirements runs pip install, which handles resolving the compatible package versions. Using a constraints file makes sure the selected packages are compatible with your Airflow version. The output will look similar to the following:

Successfully installed apache-airflow-providers-dbt-cloud-3.5.1 apache-airflow-providers-snowflake-5.2.1 pyOpenSSL-23.3.0 snowflake-connector-python-3.6.0 snowflake-sqlalchemy-1.5.1 sortedcontainers-2.4.0

The message beginning with Successfully installed is the output of interest. This shows which dependencies, and their specific version, pip installed. You use this list to create your final versioned requirements file.

Your output will also contain Requirement already satisfied messages for packages already available in the base Amazon MWAA environment. You do not add these packages to your requirements.txt file.

  1. Update the requirements file with the list of versioned packages from the test-requirements command. The updated file will look similar to the following code:
--constraint "https://raw.githubusercontent.com/apache/airflow/constraints-2.8.1/constraints-3.11.txt"
apache-airflow-providers-snowflake==5.2.1
apache-airflow-providers-dbt-cloud[http]==3.5.1
pyOpenSSL==23.3.0
snowflake-connector-python==3.6.0
snowflake-sqlalchemy==1.5.1
sortedcontainers==2.4.0

Next, you test the updated requirements file to confirm no conflicts exist.

  1. Rerun the requirements-test function:
./mwaa-local-env test-requirements

A successful test will not produce any errors. If you encounter dependency conflicts, return to the previous step and update the requirements file with additional packages, or package versions, based on pip’s output.

Package dependencies

If your Amazon MWAA environment has a private webserver, you must package your dependencies into a .zip file, upload the file to your S3 bucket, and specify the package location in your Amazon MWAA instance configuration. Because a private webserver can’t access the PyPI repository through the internet, pip will install the dependencies from the .zip file.

If you’re using a public webserver configuration, you also benefit from a static .zip file, which makes sure the package information remains unchanged until it is explicitly rebuilt.

This process uses the versioned requirements file created in the previous section and the package-requirements feature in the MWAA local runner.

To package your dependencies, complete the following steps:

  1. In a terminal, navigate to the directory where you installed the local runner.
  2. Download the constraints file for your Python version and your version of Apache Airflow and place it in the plugins directory. For this post, we use Python 3.11 and Apache Airflow v2.8.1:
curl -o plugins/constraints-2.8.1-3.11.txt https://raw.githubusercontent.com/apache/airflow/constraints-2.8.1/constraints-3.11.txt
  1. In your requirements file, update the constraints URL to the local downloaded file.

The –-constraint statement instructs pip to compare the package versions in your requirements.txt file to the allowed version in the constraints file. Downloading a specific constraints file to your plugins directory enables you to control the constraint file location and contents.

The updated requirements file will look like the following code:

--constraint "/usr/local/airflow/plugins/constraints-2.8.1-3.11.txt"
apache-airflow-providers-snowflake==5.2.1
apache-airflow-providers-dbt-cloud[http]==3.5.1
pyOpenSSL==23.3.0
snowflake-connector-python==3.6.0
snowflake-sqlalchemy==1.5.1
sortedcontainers==2.4.0
  1. Run the following command to create the .zip file:
./mwaa-local-env package-requirements

package-requirements creates an updated requirements file named packaged_requirements.txt and zips all dependencies into plugins.zip. The updated requirements file looks like the following code:

--find-links /usr/local/airflow/plugins
--no-index
--constraint "/usr/local/airflow/plugins/constraints-2.8.1-3.11.txt"
apache-airflow-providers-snowflake==5.2.1
apache-airflow-providers-dbt-cloud[http]==3.5.1
pyOpenSSL==23.3.0
snowflake-connector-python==3.6.0
snowflake-sqlalchemy==1.5.1
sortedcontainers==2.4.0

Note the reference to the local constraints file and the plugins directory. The –-find-links statement instructs pip to install packages from /usr/local/airflow/plugins rather than the public PyPI repository.

Deploy the requirements file

After you achieve an error-free requirements installation and package your dependencies, you’re ready to deploy the assets to a non-production Amazon MWAA environment. Even when verifying and testing requirements with the MWAA local runner, it’s best practice to deploy and test the changes in a non-prod Amazon MWAA environment before deploying to production. For more information about creating a CI/CD pipeline to test changes, refer to Deploying to Amazon Managed Workflows for Apache Airflow.

To deploy your changes, complete the following steps:

  1. Upload your requirements.txt file and plugins.zip file to your Amazon MWAA environment’s S3 bucket.

For instructions on specifying a requirements.txt version, refer to Specifying the requirements.txt version on the Amazon MWAA console. For instructions on specifying a plugins.zip file, refer to Installing custom plugins on your environment.

The Amazon MWAA environment will update and install the packages in your plugins.zip file.

After the update is complete, verify the provider package installation in the Apache Airflow UI.

  1. Access the Apache Airflow UI in Amazon MWAA.
  2. From the Apache Airflow menu bar, choose Admin, then Providers.

The list of providers, and their versions, is shown in a table. In this example, the page reflects the installation of apache-airflow-providers-db-cloud version 3.5.1 and apache-airflow-providers-snowflake version 5.2.1. This list only contains the provider packages installed, not all supporting Python packages. Provider packages that are part of the base Apache Airflow installation will also appear in the list. The following image is an example of the package list; note the apache-airflow-providers-db-cloud and apache-airflow-providers-snowflake packages and their versions.

Airflow UI with installed packages

To verify all package installations, view the results in Amazon CloudWatch Logs. Amazon MWAA creates a log stream for the requirements installation and the stream contains the pip install output. For instructions, refer to Viewing logs for your requirements.txt.

A successful installation results in the following message:

Successfully installed apache-airflow-providers-dbt-cloud-3.5.1 apache-airflow-providers-snowflake-5.2.1 pyOpenSSL-23.3.0 snowflake-connector-python-3.6.0 snowflake-sqlalchemy-1.5.1 sortedcontainers-2.4.0

If you encounter any installation errors, you should determine the package conflict, update the requirements file, run the local runner test, re-package the plugins, and deploy the updated files.

Clean up

If you created an Amazon MWAA environment specifically for this post, delete the environment and S3 objects to avoid incurring additional charges.

Conclusion

In this post, we discussed several best practices for managing Python dependencies in Amazon MWAA and how to use the MWAA local runner to implement these practices. These best practices reduce DAG and pip installation errors in your Amazon MWAA environment. For additional details and code examples on Amazon MWAA, visit the Amazon MWAA User Guide and the Amazon MWAA examples GitHub repo.

Apache, Apache Airflow, and Airflow are either registered trademarks or trademarks of the Apache Software Foundation in the United States and/or other countries.


About the Author


Mike Ellis is a Technical Account Manager at AWS and an Amazon MWAA specialist. In addition to assisting customers with Amazon MWAA, he contributes to the Apache Airflow open source project.