Tag Archives: announcements

Amazon Kinesis Data Streams now supports 10x larger record sizes: Simplifying real-time data processing

Post Syndicated from Sumant Nemmani original https://aws.amazon.com/blogs/big-data/amazon-kinesis-data-streams-now-supports-10x-larger-record-sizes-simplifying-real-time-data-processing/

Today, AWS announced that Amazon Kinesis Data Streams now supports record sizes up to 10MiB – a tenfold increase from the previous limit. With this launch, you can now publish intermittent larger data payloads on your data streams while continuing to use existing Kinesis Data Streams APIs in your applications without additional effort. This launch is accompanied by a 2x increase in the maximum PutRecords request size from 5MiB to 10MiB, simplifying data pipelines and reducing operational overhead for IoT analytics, change data capture, and generative AI workloads.

In this post, we explore Amazon Kinesis Data Streams large record support, including key use cases, configuration of maximum record sizes, throttling considerations, and best practices for optimal performance.

Real world use cases

As data volumes grow and use cases evolve, we’ve seen increasing demand for supporting larger record sizes in streaming workloads. Previously, when you needed to process records larger than 1MiB, you had two options:

  • Split large records into multiple smaller records in producer applications and reassemble them in consumer applications
  • Store large records in Amazon Simple Storage Service (Amazon S3) and send only metadata through Kinesis Data Streams

Both these approaches are useful, but they add complexity to data pipelines, requiring additional code, increasing operational overhead, and complicating error handling and debugging, particularly when customers need to stream large records intermittently.

This enhancement improves the ease of use and reduces operational overhead for customers handling intermittent data payloads across various industries and use cases. In the IoT analytics domain, connected vehicles and industrial equipment are generating increasing volumes of sensor telemetry data, with the size of individual telemetry records occasionally exceeding the previous 1MiB limit in Kinesis. This required customers to implement complex workarounds, such as splitting large records into multiple smaller ones or storing the large records separately and only sending metadata through Kinesis. Similarly, in database change data capture (CDC) pipelines, large transaction records can be produced, especially during bulk operations or schema changes. In the machine learning and generative AI space, workflows are increasingly requiring the ingestion of larger payloads to support richer feature sets and multi-modal data types like audio and images. The increased Kinesis record size limit from 1MiB to 10MiB limits the need for these types of complex workarounds, simplifying data pipelines and reducing operational overhead for customers in IoT, CDC, and advanced analytics use cases. Customers can now more easily ingest and process these intermittent large data records using the same familiar Kinesis APIs.

How it works

To start processing larger records:

  1. Update your stream’s maximum record size limit (maxRecordSize) through the AWS Console, AWS CLI, or AWS SDKs.
  2. Continue using the same PutRecord and PutRecords APIs for producers.
  3. Continue using the same GetRecords or SubscribeToShard APIs for consumers.

Your stream will be in Updating status for a few seconds before being ready to ingest larger records.

Getting started

To start processing larger records with Kinesis Data Streams, you can update the maximum record size by using the AWS Management Console, CLI or SDK.

On the AWS Management Console,

  1. Navigate to the Kinesis Data Streams console.
  2. Choose your stream and select the Configuration tab.
  3. Choose Edit (next to Maximum record size).
  4. Set your desired maximum record size (up to 10MiB).
  5. Save your changes.

Note: This setting only adjusts the maximum record size for this Kinesis data stream. Before increasing this limit, verify that all downstream applications can handle larger records.

Most common consumers such as Kinesis Client Library (starting with version 2.x), Amazon Data Firehose delivery to Amazon S3 and AWS Lambda support processing records larger than 1 MiB. To learn more, refer to the Amazon Kinesis Data Streams documentation for large records.

You can also update this setting using the AWS CLI:

aws kinesis update-max-record-size \
--stream-arn <stream-arn> \
--max-record-size-in-ki-b 5000

Or using the AWS SDK:

import boto3

client = boto3.client('kinesis')
response = client.update_max_record_size(
StreamARN='arn:aws:kinesis:us-west-2:123456789012:stream/my-stream',
MaxRecordSizeInKiB=5000
)

Throttling and best practices for optimal performance

Individual shard throughput limits of 1MiB/s for writes and 2MiB/s for reads remain unchanged with support for larger record sizes. To work with large records, let’s understand how throttling works. In a stream, each shard has a throughput capacity of 1 MiB per second. To accommodate large records, each shard temporarily bursts up to 10MiB/s, eventually averaging out to 1MiB per second. To help visualize this behavior, think of each shard having a capacity tank that refills at 1MiB per second. After sending a large record (for example, a 10MiB record), the tank begins refilling immediately, allowing you to send smaller records as capacity becomes available. This capacity to support large records is continuously refilled into the stream. The rate of refilling depends on the size of the large records, the size of the baseline record, the overall traffic pattern, and your chosen partition key strategy. When you process large records, each shard continues to process baseline traffic while leveraging its burst capacity to handle these larger payloads.

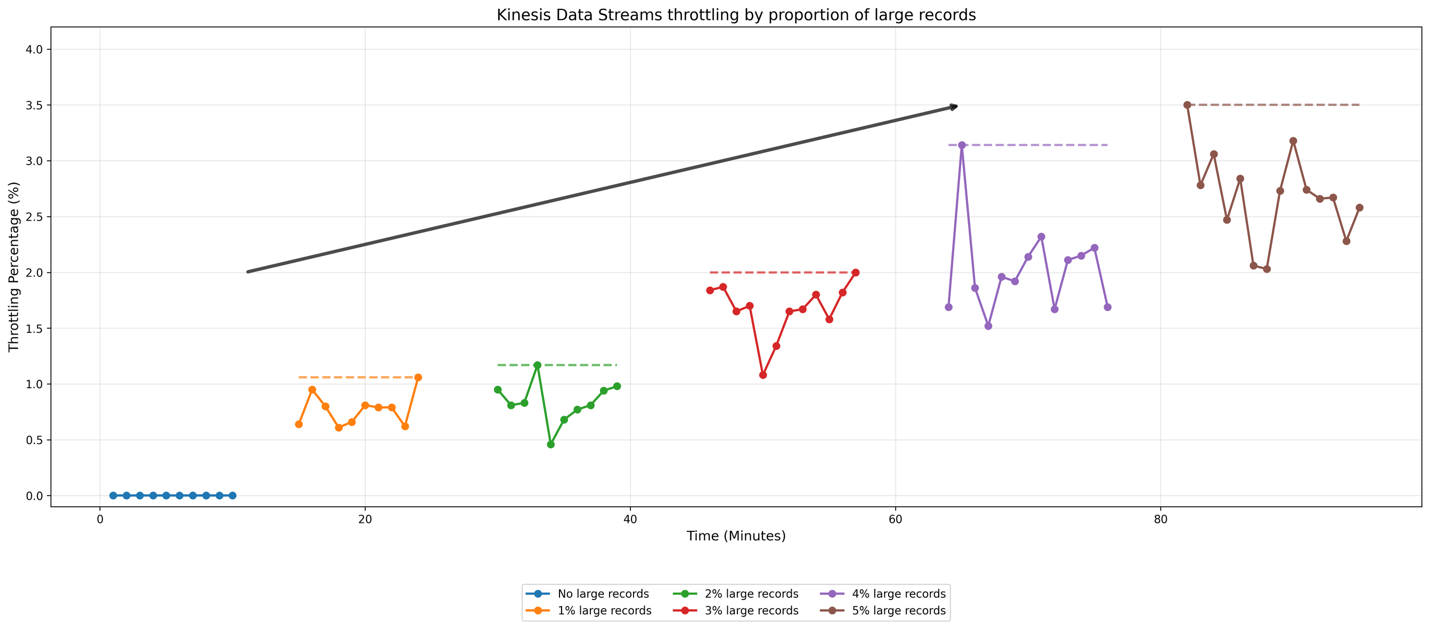
To illustrate how Kinesis Data Streams handles different proportions of large records, let’s examine the results a simple test. For our test configuration, we set up a producer that sends data to an on-demand stream (defaults to 4 shards) at a rate of 50 records per second. The baseline records are 10KiB in size, while large records are 2MiB each. We conducted multiple test cases by progressively increasing the proportion of large records from 1% to 5% of the total stream traffic, along with a baseline case containing no large records. To ensure consistent testing conditions, we distributed the large records uniformly over time for example, in the 1% scenario, we sent one large record for every 100 baseline records. The following graph shows the results:

In the graph, horizontal annotations indicate throttling occurrence peaks. The baseline scenario, represented by the blue line, shows minimal throttling events. As the proportion of large records increases from 1% to 5%, we observe an increase in the rate at which your stream throttles your data, with a notable acceleration in throttling events between the 2% and 5% scenarios. This test demonstrates how Kinesis Data Streams manages increasing proportion of large records.

We recommend maintaining large records at 1-2% of your total record count for optimal performance. In production environments, actual stream behavior varies based on three key factors: the size of baseline records, the size of large records, and the frequency at which large records appear in the stream. We recommend that you test with your demand pattern to determine the specific behavior.

With on-demand streams, when the incoming traffic exceeds 500 KB/s per shard, it splits the shard within 15 minutes. The parent shard’s hash key values are redistributed evenly across child shards. Kinesis automatically scales the stream to increase the number of shards, enabling distribution of large records across a larger number of shards depending on the partition key strategy employed.

For optimal performance with large records:

  1. Use a random partition key strategy to distribute large records evenly across shards.
  2. Implement backoff and retry logic in producer applications.
  3. Monitor shard-level metrics to identify potential bottlenecks.

If you still need to continuously stream of large records, consider using Amazon S3 to store payloads and send only metadata references to the stream. Refer to Processing large records with Amazon Kinesis Data Streams for more information.

Conclusion

Amazon Kinesis Data Streams now supports record sizes up to 10MiB, a tenfold increase from the previous 1MiB limit. This enhancement simplifies data pipelines for IoT analytics, change data capture, and AI/ML workloads by eliminating the need for complex workarounds. You can continue using existing Kinesis Data Streams APIs without additional code changes and benefit from increased flexibility in handling intermittent large payloads.

  • For optimal performance, we recommend maintaining large records at 1-2% of total record count.
  • For best results with large records, implement a uniformly distributed partition key strategy to evenly distribute records across shards, include backoff and retry logic in producer applications, and monitor shard-level metrics to identify potential bottlenecks.
  • Before increasing the maximum record size, verify that all downstream applications and consumers can handle larger records.

We’re excited to see how you’ll leverage this capability to build more powerful and efficient streaming applications. To learn more, visit the Amazon Kinesis Data Streams documentation.


About the authors

Sumant Nemmani

Sumant Nemmani

Sumant is a product manager for Amazon Kinesis Data Streams. He is passionate about learning from customers and enjoys helping them unlock value with AWS. Outside of work, he spends time making music with his band Project Mishram, exploring history and food while traveling, and long-form podcasts on technology and history.

Umesh Chaudhari

Umesh Chaudhari

Umesh is a Sr. Streaming Solutions Architect at AWS. He works with customers to design and build real-time data processing systems. He has extensive working experience in software engineering, including architecting, designing, and developing data analytics systems. Outside of work, he enjoys traveling, following tech trends

Pratik Patel

Pratik Patel

Pratik is Sr. Technical Account Manager and streaming analytics specialist. He works with AWS customers and provides ongoing support and technical guidance to help plan and build solutions using best practices and proactively keep customers’ AWS environments operationally healthy.

Amazon Nova Multimodal Embeddings: State-of-the-art embedding model for agentic RAG and semantic search

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/amazon-nova-multimodal-embeddings-now-available-in-amazon-bedrock/

Today, we’re introducing Amazon Nova Multimodal Embeddings, a state-of-the-art multimodal embedding model for agentic retrieval-augmented generation (RAG) and semantic search applications, available in Amazon Bedrock. It is the first unified embedding model that supports text, documents, images, video, and audio through a single model to enable crossmodal retrieval with leading accuracy.

Embedding models convert textual, visual, and audio inputs into numerical representations called embeddings. These embeddings capture the meaning of the input in a way that AI systems can compare, search, and analyze, powering use cases such as semantic search and RAG.

Organizations are increasingly seeking solutions to unlock insights from the growing volume of unstructured data that is spread across text, image, document, video, and audio content. For example, an organization might have product images, brochures that contain infographics and text, and user-uploaded video clips. Embedding models are able to unlock value from unstructured data, however traditional models are typically specialized to handle one content type. This limitation drives customers to either build complex crossmodal embedding solutions or restrict themselves to use cases focused on a single content type. The problem also applies to mixed-modality content types such as documents with interleaved text and images or video with visual, audio, and textual elements where existing models struggle to capture crossmodal relationships effectively.

Nova Multimodal Embeddings supports a unified semantic space for text, documents, images, video, and audio for use cases such as crossmodal search across mixed-modality content, searching with a reference image, and retrieving visual documents.

Evaluating Amazon Nova Multimodal Embeddings performance
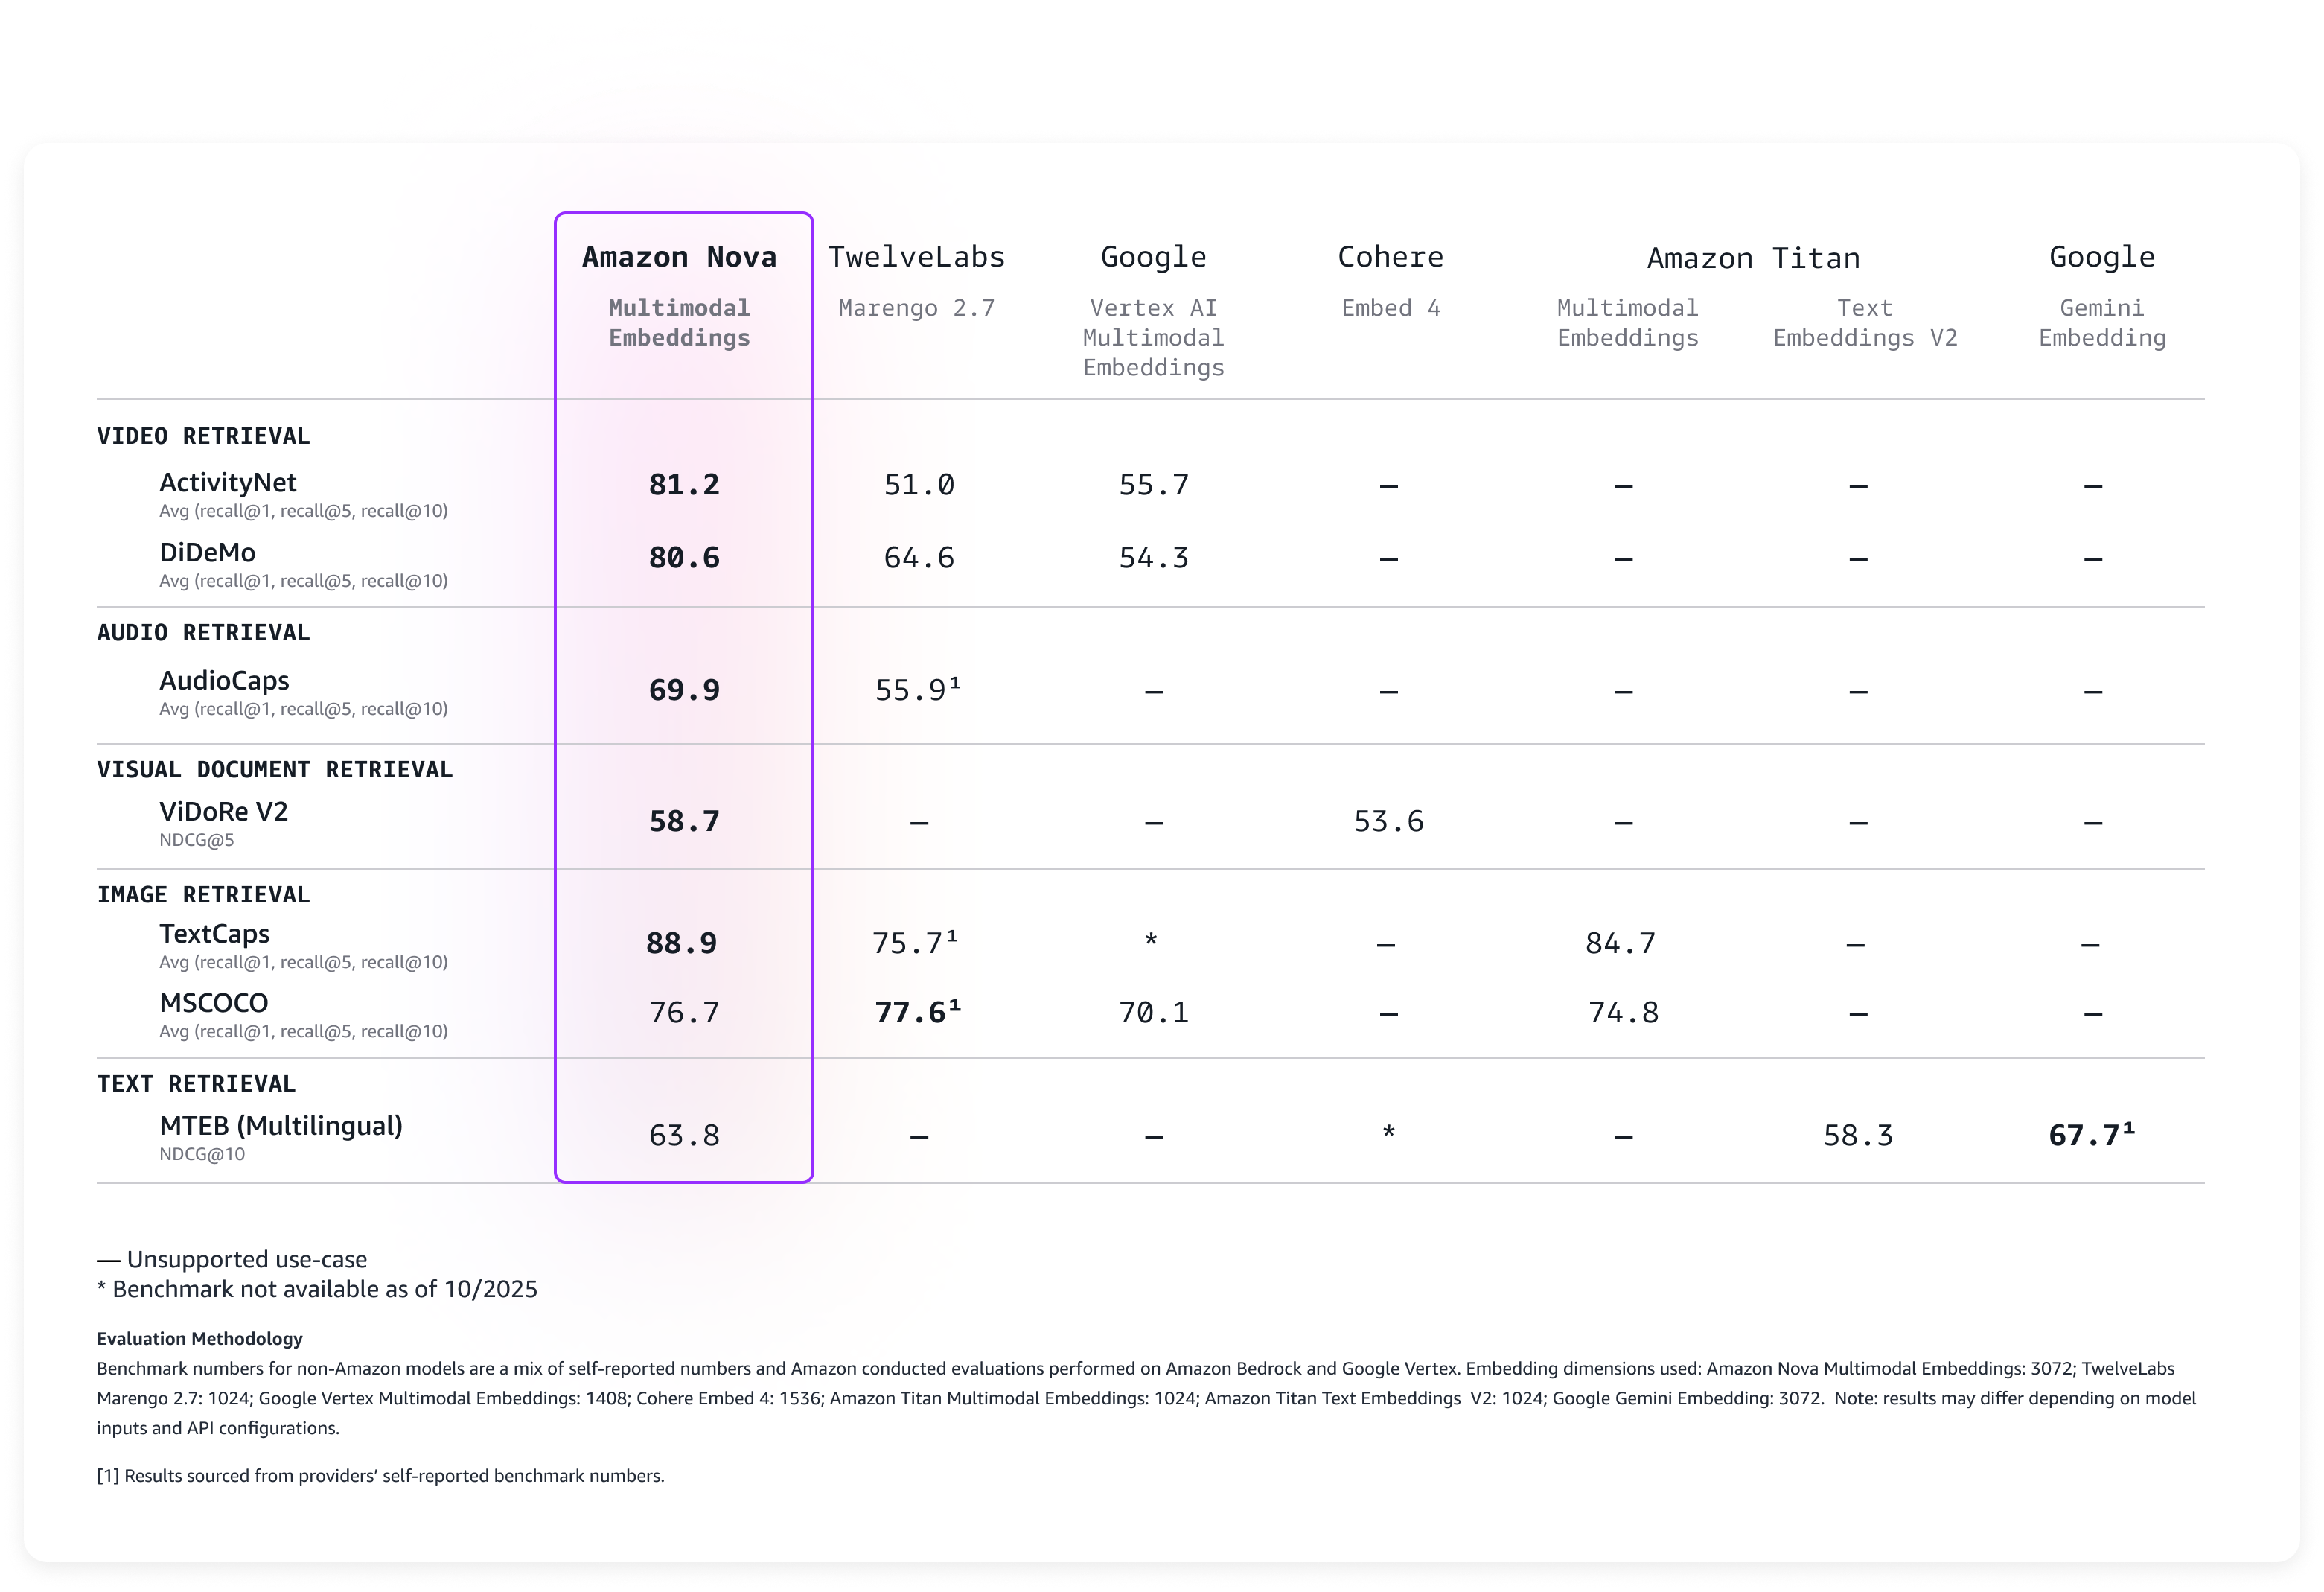
We evaluated the model on a broad range of benchmarks, and it delivers leading accuracy out-of-the-box as described in the following table.

Amazon Nova Embeddings benchmarks

Nova Multimodal Embeddings supports a context length of up to 8K tokens, text in up to 200 languages, and accepts inputs via synchronous and asynchronous APIs. Additionally, it supports segmentation (also known as “chunking”) to partition long-form text, video, or audio content into manageable segments, generating embeddings for each portion. Lastly, the model offers four output embedding dimensions, trained using Matryoshka Representation Learning (MRL) that enables low-latency end-to-end retrieval with minimal accuracy changes.

Let’s see how the new model can be used in practice.

Using Amazon Nova Multimodal Embeddings
Getting started with Nova Multimodal Embeddings follows the same pattern as other models in Amazon Bedrock. The model accepts text, documents, images, video, or audio as input and returns numerical embeddings that you can use for semantic search, similarity comparison, or RAG.

Here’s a practical example using the AWS SDK for Python (Boto3) that shows how to create embeddings from different content types and store them for later retrieval. For simplicity, I’ll use Amazon S3 Vectors, a cost-optimized storage with native support for storing and querying vectors at any scale, to store and search the embeddings.

Let’s start with the fundamentals: converting text into embeddings. This example shows how to transform a simple text description into a numerical representation that captures its semantic meaning. These embeddings can later be compared with embeddings from documents, images, videos, or audio to find related content.

To make the code easy to follow, I’ll show a section of the script at a time. The full script is included at the end of this walkthrough.

import json
import base64
import time
import boto3

MODEL_ID = "amazon.nova-2-multimodal-embeddings-v1:0"
EMBEDDING_DIMENSION = 3072

# Initialize Amazon Bedrock Runtime client
bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")

print(f"Generating text embedding with {MODEL_ID} ...")

# Text to embed
text = "Amazon Nova is a multimodal foundation model"

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "text": {"truncationMode": "END", "value": text},
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")

Now we’ll process visual content using the same embedding space using a photo.jpg file in the same folder as the script. This demonstrates the power of multimodality: Nova Multimodal Embeddings is able to capture both textual and visual context into a single embedding that provides enhanced understanding of the document.

Nova Multimodal Embeddings can generate embeddings that are optimized for how they are being used. When indexing for a search or retrieval use case, embeddingPurpose can be set to GENERIC_INDEX. For the query step, embeddingPurpose can be set depending on the type of item to be retrieved. For example, when retrieving documents, embeddingPurpose can be set to DOCUMENT_RETRIEVAL.

# Read and encode image
print(f"Generating image embedding with {MODEL_ID} ...")

with open("photo.jpg", "rb") as f:
    image_bytes = base64.b64encode(f.read()).decode("utf-8")

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "image": {
            "format": "jpeg",
            "source": {"bytes": image_bytes}
        },
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")

To process video content, I use the asynchronous API. That’s a requirement for videos that are larger than 25MB when encoded as Base64. First, I upload a local video to an S3 bucket in the same AWS Region.

aws s3 cp presentation.mp4 s3://my-video-bucket/videos/

This example shows how to extract embeddings from both visual and audio components of a video file. The segmentation feature breaks longer videos into manageable chunks, making it practical to search through hours of content efficiently.

# Initialize Amazon S3 client
s3 = boto3.client("s3", region_name="us-east-1")

print(f"Generating video embedding with {MODEL_ID} ...")

# Amazon S3 URIs
S3_VIDEO_URI = "s3://my-video-bucket/videos/presentation.mp4"
S3_EMBEDDING_DESTINATION_URI = "s3://my-embedding-destination-bucket/embeddings-output/"

# Create async embedding job for video with audio
model_input = {
    "taskType": "SEGMENTED_EMBEDDING",
    "segmentedEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "video": {
            "format": "mp4",
            "embeddingMode": "AUDIO_VIDEO_COMBINED",
            "source": {
                "s3Location": {"uri": S3_VIDEO_URI}
            },
            "segmentationConfig": {
                "durationSeconds": 15  # Segment into 15-second chunks
            },
        },
    },
}

response = bedrock_runtime.start_async_invoke(
    modelId=MODEL_ID,
    modelInput=model_input,
    outputDataConfig={
        "s3OutputDataConfig": {
            "s3Uri": S3_EMBEDDING_DESTINATION_URI
        }
    },
)

invocation_arn = response["invocationArn"]
print(f"Async job started: {invocation_arn}")

# Poll until job completes
print("\nPolling for job completion...")
while True:
    job = bedrock_runtime.get_async_invoke(invocationArn=invocation_arn)
    status = job["status"]
    print(f"Status: {status}")

    if status != "InProgress":
        break
    time.sleep(15)

# Check if job completed successfully
if status == "Completed":
    output_s3_uri = job["outputDataConfig"]["s3OutputDataConfig"]["s3Uri"]
    print(f"\nSuccess! Embeddings at: {output_s3_uri}")

    # Parse S3 URI to get bucket and prefix
    s3_uri_parts = output_s3_uri[5:].split("/", 1)  # Remove "s3://" prefix
    bucket = s3_uri_parts[0]
    prefix = s3_uri_parts[1] if len(s3_uri_parts) > 1 else ""

    # AUDIO_VIDEO_COMBINED mode outputs to embedding-audio-video.jsonl
    # The output_s3_uri already includes the job ID, so just append the filename
    embeddings_key = f"{prefix}/embedding-audio-video.jsonl".lstrip("/")

    print(f"Reading embeddings from: s3://{bucket}/{embeddings_key}")

    # Read and parse JSONL file
    response = s3.get_object(Bucket=bucket, Key=embeddings_key)
    content = response['Body'].read().decode('utf-8')

    embeddings = []
    for line in content.strip().split('\n'):
        if line:
            embeddings.append(json.loads(line))

    print(f"\nFound {len(embeddings)} video segments:")
    for i, segment in enumerate(embeddings):
        print(f"  Segment {i}: {segment.get('startTime', 0):.1f}s - {segment.get('endTime', 0):.1f}s")
        print(f"    Embedding dimension: {len(segment.get('embedding', []))}")
else:
    print(f"\nJob failed: {job.get('failureMessage', 'Unknown error')}")

With our embeddings generated, we need a place to store and search them efficiently. This example demonstrates setting up a vector store using Amazon S3 Vectors, which provides the infrastructure needed for similarity search at scale. Think of this as creating a searchable index where semantically similar content naturally clusters together. When adding an embedding to the index, I use the metadata to specify the original format and the content being indexed.

# Initialize Amazon S3 Vectors client
s3vectors = boto3.client("s3vectors", region_name="us-east-1")

# Configuration
VECTOR_BUCKET = "my-vector-store"
INDEX_NAME = "embeddings"

# Create vector bucket and index (if they don't exist)
try:
    s3vectors.get_vector_bucket(vectorBucketName=VECTOR_BUCKET)
    print(f"Vector bucket {VECTOR_BUCKET} already exists")
except s3vectors.exceptions.NotFoundException:
    s3vectors.create_vector_bucket(vectorBucketName=VECTOR_BUCKET)
    print(f"Created vector bucket: {VECTOR_BUCKET}")

try:
    s3vectors.get_index(vectorBucketName=VECTOR_BUCKET, indexName=INDEX_NAME)
    print(f"Vector index {INDEX_NAME} already exists")
except s3vectors.exceptions.NotFoundException:
    s3vectors.create_index(
        vectorBucketName=VECTOR_BUCKET,
        indexName=INDEX_NAME,
        dimension=EMBEDDING_DIMENSION,
        dataType="float32",
        distanceMetric="cosine"
    )
    print(f"Created index: {INDEX_NAME}")

texts = [
    "Machine learning on AWS",
    "Amazon Bedrock provides foundation models",
    "S3 Vectors enables semantic search"
]

print(f"\nGenerating embeddings for {len(texts)} texts...")

# Generate embeddings using Amazon Nova for each text
vectors = []
for text in texts:
    response = bedrock_runtime.invoke_model(
        body=json.dumps({
            "taskType": "SINGLE_EMBEDDING",
            "singleEmbeddingParams": {
                "embeddingDimension": EMBEDDING_DIMENSION,
                "text": {"truncationMode": "END", "value": text}
            }
        }),
        modelId=MODEL_ID,
        accept="application/json",
        contentType="application/json"
    )

    response_body = json.loads(response["body"].read())
    embedding = response_body["embeddings"][0]["embedding"]

    vectors.append({
        "key": f"text:{text[:50]}",  # Unique identifier
        "data": {"float32": embedding},
        "metadata": {"type": "text", "content": text}
    })
    print(f"  ✓ Generated embedding for: {text}")

# Add all vectors to store in a single call
s3vectors.put_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    vectors=vectors
)

print(f"\nSuccessfully added {len(vectors)} vectors to the store in one put_vectors call!")

This final example demonstrates the capability of searching across different content types with a single query, finding the most similar content regardless of whether it originated from text, images, videos, or audio. The distance scores help you understand how closely related the results are to your original query.

# Text to query
query_text = "foundation models"  

print(f"\nGenerating embeddings for query '{query_text}' ...")

# Generate embeddings
response = bedrock_runtime.invoke_model(
    body=json.dumps({
        "taskType": "SINGLE_EMBEDDING",
        "singleEmbeddingParams": {
            "embeddingPurpose": "GENERIC_RETRIEVAL",
            "embeddingDimension": EMBEDDING_DIMENSION,
            "text": {"truncationMode": "END", "value": query_text}
        }
    }),
    modelId=MODEL_ID,
    accept="application/json",
    contentType="application/json"
)

response_body = json.loads(response["body"].read())
query_embedding = response_body["embeddings"][0]["embedding"]

print(f"Searching for similar embeddings...\n")

# Search for top 5 most similar vectors
response = s3vectors.query_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    queryVector={"float32": query_embedding},
    topK=5,
    returnDistance=True,
    returnMetadata=True
)

# Display results
print(f"Found {len(response['vectors'])} results:\n")
for i, result in enumerate(response["vectors"], 1):
    print(f"{i}. {result['key']}")
    print(f"   Distance: {result['distance']:.4f}")
    if result.get("metadata"):
        print(f"   Metadata: {result['metadata']}")
    print()

Crossmodal search is one of the key advantages of multimodal embeddings. With crossmodal search, you can query with text and find relevant images. You can also search for videos using text descriptions, find audio clips that match certain topics, or discover documents based on their visual and textual content. For your reference, the full script with all previous examples merged together is here:

import json
import base64
import time
import boto3

MODEL_ID = "amazon.nova-2-multimodal-embeddings-v1:0"
EMBEDDING_DIMENSION = 3072

# Initialize Amazon Bedrock Runtime client
bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")

print(f"Generating text embedding with {MODEL_ID} ...")

# Text to embed
text = "Amazon Nova is a multimodal foundation model"

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "text": {"truncationMode": "END", "value": text},
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")
# Read and encode image
print(f"Generating image embedding with {MODEL_ID} ...")

with open("photo.jpg", "rb") as f:
    image_bytes = base64.b64encode(f.read()).decode("utf-8")

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "image": {
            "format": "jpeg",
            "source": {"bytes": image_bytes}
        },
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")
# Initialize Amazon S3 client
s3 = boto3.client("s3", region_name="us-east-1")

print(f"Generating video embedding with {MODEL_ID} ...")

# Amazon S3 URIs
S3_VIDEO_URI = "s3://my-video-bucket/videos/presentation.mp4"

# Amazon S3 output bucket and location
S3_EMBEDDING_DESTINATION_URI = "s3://my-video-bucket/embeddings-output/"

# Create async embedding job for video with audio
model_input = {
    "taskType": "SEGMENTED_EMBEDDING",
    "segmentedEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "video": {
            "format": "mp4",
            "embeddingMode": "AUDIO_VIDEO_COMBINED",
            "source": {
                "s3Location": {"uri": S3_VIDEO_URI}
            },
            "segmentationConfig": {
                "durationSeconds": 15  # Segment into 15-second chunks
            },
        },
    },
}

response = bedrock_runtime.start_async_invoke(
    modelId=MODEL_ID,
    modelInput=model_input,
    outputDataConfig={
        "s3OutputDataConfig": {
            "s3Uri": S3_EMBEDDING_DESTINATION_URI
        }
    },
)

invocation_arn = response["invocationArn"]
print(f"Async job started: {invocation_arn}")

# Poll until job completes
print("\nPolling for job completion...")
while True:
    job = bedrock_runtime.get_async_invoke(invocationArn=invocation_arn)
    status = job["status"]
    print(f"Status: {status}")

    if status != "InProgress":
        break
    time.sleep(15)

# Check if job completed successfully
if status == "Completed":
    output_s3_uri = job["outputDataConfig"]["s3OutputDataConfig"]["s3Uri"]
    print(f"\nSuccess! Embeddings at: {output_s3_uri}")

    # Parse S3 URI to get bucket and prefix
    s3_uri_parts = output_s3_uri[5:].split("/", 1)  # Remove "s3://" prefix
    bucket = s3_uri_parts[0]
    prefix = s3_uri_parts[1] if len(s3_uri_parts) > 1 else ""

    # AUDIO_VIDEO_COMBINED mode outputs to embedding-audio-video.jsonl
    # The output_s3_uri already includes the job ID, so just append the filename
    embeddings_key = f"{prefix}/embedding-audio-video.jsonl".lstrip("/")

    print(f"Reading embeddings from: s3://{bucket}/{embeddings_key}")

    # Read and parse JSONL file
    response = s3.get_object(Bucket=bucket, Key=embeddings_key)
    content = response['Body'].read().decode('utf-8')

    embeddings = []
    for line in content.strip().split('\n'):
        if line:
            embeddings.append(json.loads(line))

    print(f"\nFound {len(embeddings)} video segments:")
    for i, segment in enumerate(embeddings):
        print(f"  Segment {i}: {segment.get('startTime', 0):.1f}s - {segment.get('endTime', 0):.1f}s")
        print(f"    Embedding dimension: {len(segment.get('embedding', []))}")
else:
    print(f"\nJob failed: {job.get('failureMessage', 'Unknown error')}")
# Initialize Amazon S3 Vectors client
s3vectors = boto3.client("s3vectors", region_name="us-east-1")

# Configuration
VECTOR_BUCKET = "my-vector-store"
INDEX_NAME = "embeddings"

# Create vector bucket and index (if they don't exist)
try:
    s3vectors.get_vector_bucket(vectorBucketName=VECTOR_BUCKET)
    print(f"Vector bucket {VECTOR_BUCKET} already exists")
except s3vectors.exceptions.NotFoundException:
    s3vectors.create_vector_bucket(vectorBucketName=VECTOR_BUCKET)
    print(f"Created vector bucket: {VECTOR_BUCKET}")

try:
    s3vectors.get_index(vectorBucketName=VECTOR_BUCKET, indexName=INDEX_NAME)
    print(f"Vector index {INDEX_NAME} already exists")
except s3vectors.exceptions.NotFoundException:
    s3vectors.create_index(
        vectorBucketName=VECTOR_BUCKET,
        indexName=INDEX_NAME,
        dimension=EMBEDDING_DIMENSION,
        dataType="float32",
        distanceMetric="cosine"
    )
    print(f"Created index: {INDEX_NAME}")

texts = [
    "Machine learning on AWS",
    "Amazon Bedrock provides foundation models",
    "S3 Vectors enables semantic search"
]

print(f"\nGenerating embeddings for {len(texts)} texts...")

# Generate embeddings using Amazon Nova for each text
vectors = []
for text in texts:
    response = bedrock_runtime.invoke_model(
        body=json.dumps({
            "taskType": "SINGLE_EMBEDDING",
            "singleEmbeddingParams": {
                "embeddingPurpose": "GENERIC_INDEX",
                "embeddingDimension": EMBEDDING_DIMENSION,
                "text": {"truncationMode": "END", "value": text}
            }
        }),
        modelId=MODEL_ID,
        accept="application/json",
        contentType="application/json"
    )

    response_body = json.loads(response["body"].read())
    embedding = response_body["embeddings"][0]["embedding"]

    vectors.append({
        "key": f"text:{text[:50]}",  # Unique identifier
        "data": {"float32": embedding},
        "metadata": {"type": "text", "content": text}
    })
    print(f"  ✓ Generated embedding for: {text}")

# Add all vectors to store in a single call
s3vectors.put_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    vectors=vectors
)

print(f"\nSuccessfully added {len(vectors)} vectors to the store in one put_vectors call!")
# Text to query
query_text = "foundation models"  

print(f"\nGenerating embeddings for query '{query_text}' ...")

# Generate embeddings
response = bedrock_runtime.invoke_model(
    body=json.dumps({
        "taskType": "SINGLE_EMBEDDING",
        "singleEmbeddingParams": {
            "embeddingPurpose": "GENERIC_RETRIEVAL",
            "embeddingDimension": EMBEDDING_DIMENSION,
            "text": {"truncationMode": "END", "value": query_text}
        }
    }),
    modelId=MODEL_ID,
    accept="application/json",
    contentType="application/json"
)

response_body = json.loads(response["body"].read())
query_embedding = response_body["embeddings"][0]["embedding"]

print(f"Searching for similar embeddings...\n")

# Search for top 5 most similar vectors
response = s3vectors.query_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    queryVector={"float32": query_embedding},
    topK=5,
    returnDistance=True,
    returnMetadata=True
)

# Display results
print(f"Found {len(response['vectors'])} results:\n")
for i, result in enumerate(response["vectors"], 1):
    print(f"{i}. {result['key']}")
    print(f"   Distance: {result['distance']:.4f}")
    if result.get("metadata"):
        print(f"   Metadata: {result['metadata']}")
    print()

For production applications, embeddings can be stored in any vector database. Amazon OpenSearch Service offers native integration with Nova Multimodal Embeddings at launch, making it straightforward to build scalable search applications. As shown in the examples before, Amazon S3 Vectors provides a simple way to store and query embeddings with your application data.

Things to know
Nova Multimodal Embeddings offers four output dimension options: 3,072, 1,024, 384, and 256. Larger dimensions provide more detailed representations but require more storage and computation. Smaller dimensions offer a practical balance between retrieval performance and resource efficiency. This flexibility helps you optimize for your specific application and cost requirements.

The model handles substantial context lengths. For text inputs, it can process up to 8,192 tokens at once. Video and audio inputs support segments of up to 30 seconds, and the model can segment longer files. This segmentation capability is particularly useful when working with large media files—the model splits them into manageable pieces and creates embeddings for each segment.

The model includes responsible AI features built into Amazon Bedrock. Content submitted for embedding goes through Amazon Bedrock content safety filters, and the model includes fairness measures to reduce bias.

As described in the code examples, the model can be invoked through both synchronous and asynchronous APIs. The synchronous API works well for real-time applications where you need immediate responses, such as processing user queries in a search interface. The asynchronous API handles latency insensitive workloads more efficiently, making it suitable for processing large content such as videos.

Availability and pricing
Amazon Nova Multimodal Embeddings is available today in Amazon Bedrock in the US East (N. Virginia) AWS Region. For detailed pricing information, visit the Amazon Bedrock pricing page.

To learn more, see the Amazon Nova User Guide for comprehensive documentation and the Amazon Nova model cookbook on GitHub for practical code examples.

If you’re using an AI–powered assistant for software development such as Amazon Q Developer or Kiro, you can set up the AWS API MCP Server to help the AI assistants interact with AWS services and resources and the AWS Knowledge MCP Server to provide up-to-date documentation, code samples, knowledge about the regional availability of AWS APIs and CloudFormation resources.

Start building multimodal AI-powered applications with Nova Multimodal Embeddings today, and share your feedback through AWS re:Post for Amazon Bedrock or your usual AWS Support contacts.

— Danilo
Processing Amazon S3 objects at scale with AWS Step Functions Distributed Map S3 prefix

Post Syndicated from Biswanath Mukherjee original https://aws.amazon.com/blogs/compute/processing-amazon-s3-objects-at-scale-with-aws-step-functions-distributed-map-s3-prefix/

If you’re building large scale enterprise applications, you’ve likely faced the complexities of processing large volumes of data files. Whether you’re analyzing your application logs, processing customer data files, or transforming machine learning datasets, you know the complexity involved in orchestrating workflows. You’ve probably written nested workflows and additional custom code to process objects from Amazon Simple Storage Service (Amazon S3) buckets.

With AWS Step Functions Distributed Map, you can process large scale datasets by running concurrent iterations of workflow steps across data entries in parallel, achieving massive scale with simplified management.

With the new prefix-based iteration feature and LOAD_AND_FLATTEN transformation parameter for Distributed Map, your workflows can now iterate over S3 objects under a specified prefix using S3ListObjectsV2 to process their contents in a single Map state, avoiding nested workflows and reducing operational complexity.

In this post, you’ll learn how to process Amazon S3 objects at scale with the new AWS Step Functions Distributed Map S3 prefix and transformation capabilities.

Use case: Application log processing and summarization

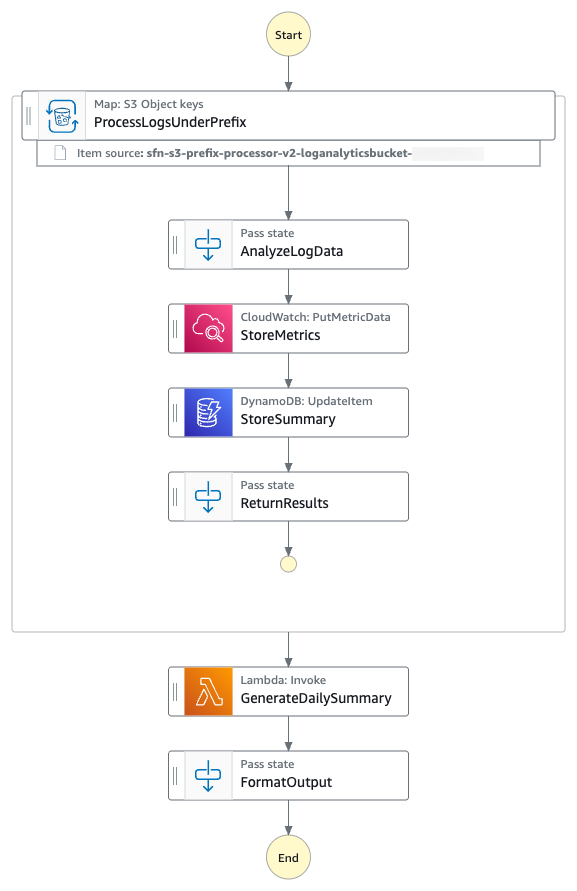
You’ll build a sample Step Functions state machine that demonstrates processing of all the log files from the given S3 prefix using a Distributed Map. You’ll analyze all the log files to build a summary INFO, WARNING and ERROR messages in the log file on hourly basis. The following diagram presents the AWS Step Functions state machine:

Log files processing workflow

Log files processing workflow

  1. The state machine iterates over all the log files from the specified S3 prefix using S3 ListObjectsV2 and process them using AWS Step Functions Distributed Map.
  2. For each log file entry, the state machine puts hourly ErrorCount metric into Amazon CloudWatch.
  3. The state machine then stores hourly metrics count in a Amazon DynamoDB table.
  4. The state machine then invokes an AWS Lambda function to perform metrics aggregation.

The following is an example of the parameters in an ItemReader configured to iterate over the content of S3 objects using S3 ListObjectsV2.

{
  "QueryLanguage": "JSONata",
  "States": {
    ...
    "Map": {
        ...
        "ItemReader": {
            "Resource": "arn:aws:states:::s3:listObjectsV2",
            "ReaderConfig": {
                // InputType is required if Transformation is LOAD_AND_FLATTEN. Use one of the given values
                "InputType": "CSV | JSON | JSONL | PARQUET",
                // Transformation is OPTIONAL and defaults to NONE if not present
                "Transformation": "NONE | LOAD_AND_FLATTEN" 
            },
            "Arguments": {
                "Bucket": "amzn-s3-demo-bucket1",
                "Prefix": "{% $states.input.PrefixKey %}"
            }
        },
        ...
    }
}

With the LOAD_AND_FLATTEN option, your state machine will do the following:

  1. Read the actual content of each object listed by the Amazon S3 ListObjectsV2 call.
  2. Parse the content based on InputType (CSV, JSON, JSONL, Parquet).
  3. Create items from the file contents (rows/records) rather than metadata.

We recommend including a trailing slash on your prefix. For example, if you select data with a prefix of folder1, your state machine will process both folder1/myData.csv and folder10/myData.csv. Using folder1/ will strictly process only one folder. All of the objects listed by prefix need to be in the same data format. For example, if you are selecting InputType as JSONL, your S3 prefix should contain only JSONL files and not a mix of other types.

The context object is an internal JSON structure that is available during an execution. The context object contains information about your state machine and execution. Your workflows can reference the context object in a JSONata expression with $states.context.

Within a Map state, the context object includes the following data:

"Map": {
   "Item": {
      "Index" : Number,
      "Key"   : "String", // Only valid for JSON objects
      "Value" : "String",
      "Source": "String"
   }
}

For each Map iteration, the Index contains the index number for the array item that is being currently processed.

A Key is only available when iterating over JSON objects. Value contains the array item being processed. For example, for the following input JSON object, Names will be assigned to Key and {"Bob", "Cat"} will be assigned to Value.

{
	"Names": {"Bob", "Cat"}
} 

Source contains one of the following:

  • For state input: STATE_DATA
  • For Amazon S3 LIST_OBJECTS_V2 with Transformation=NONE, the value will show the S3 URI for the bucket. For example: S3://amzn-s3-demo-bucket1
  • For all the other input types, the value will be the Amazon S3 URI. For example: S3://amzn-s3-demo-bucket1/object-key

Using LOAD_AND_FLATTEN and the Source field, you can connect child executions to their sources.

Prerequisites

Set up and run the workflow

Run the following steps to deploy and test the Step Functions state machine.

  1. Clone the GitHub repository in a new folder and navigate to the project folder.
    git clone https://github.com/aws-samples/sample-stepfunctions-s3-prefix-processor.git
    cd sample-stepfunctions-s3-prefix-processor

  2. Run the following commands to deploy the application.
    sam deploy --guided

  3. Enter the following details:
    • Stack name: Stack name for CloudFormation (for example, stepfunctions-s3-prefix-processor)
    • AWS Region: A supported AWS Region (for example, us-east-1)
    • Accept all other default values.

    The outputs from the AWS SAM deploy will be used in the subsequent steps.

  4. Run the following command to generate sample log files.
    python3 scripts/generate_logs.py

  5. Run the following to upload the log files to the S3 bucket with the /logs/daily prefix. Replace amzn-s3-demo-bucket1 with the value from the sam deploy output.
    aws s3 sync logs/ s3://amzn-s3-demo-bucket1/logs/ --exclude '*' --include '*.log'

  6. Run the following command to execute the Step Functions workflow. Replace the StateMachineArn with the value from the sam deploy output.
    aws stepfunctions start-execution \
      --state-machine-arn <StateMachineArn> \
      --input '{}'

    The Step Function state machine iterates over all the log files with the S3 prefix /logs/daily and processes them in parallel. The workflow updates the metrics in CloudWatch, stores hourly metrics count in DynamoDB, then invokes an AWS Lambda function to aggregate the metrics.

Monitor and verify results

Run the following steps to monitor and verify the test results.

  1. Run the following command to get the details of the execution. Replace executionArn with your state machine ARN.
    aws stepfunctions describe-execution --execution-arn <executionArn>

  2. When the status shows SUCCEEDED, run the following commands to check the processed output from the LogAnalyticsSummaryTableName DynamoDB table. Replace the value LogAnalyticsSummaryTableName with the value from the sam deploy output.
    aws dynamodb scan --table-name <LogAnalyticsSummaryTableName>

  3. Check that hourly ERROR, WARN, and INFO logs statistics are saved in the DynamoDB table. The following is a sample output:
    {
        "Items": [
            {
                "ProcessingTime": {
                    "S": "2025-10-07T23:45:10.790Z"
                },
                "WarningCount": {
                    "N": "2"
                },
                "HourOfDay": {
                    "S": "13"
                },
                "TotalRecords": {
                    "N": "5"
                },
                "ErrorCount": {
                    "N": "3"
                },
                "InfoCount": {
                    "N": "0"
                },
                "HourKey": {
                    "S": "2025-10-08 13"
                }
            },
            {
                "ProcessingTime": {
                    "S": "2025-10-07T23:45:07.456Z"
                },
                "WarningCount": {
                    "N": "3"
                },
                "HourOfDay": {
                    "S": "09"
                },
                "TotalRecords": {
                    "N": "6"
                },
                "ErrorCount": {
                    "N": "2"
                },
                "InfoCount": {
                    "N": "1"
                },
                "HourKey": {
                    "S": "2025-10-08 09"
                }
            },
            …
    ],
        "Count": 24,
        "ScannedCount": 24,
        "ConsumedCapacity": null
    }

  4. Run the following command to check the output of the Step Functions state machine execution output.
    aws stepfunctions describe-execution --execution-arn <executionArn> --query 'output' --output text

    The following is a sample output:

    {
      "Summary": {
        "date": "2025-10-08",
        "totalErrors": 50,
        "totalWarnings": 41,
        "totalRecords": 133,
        "hourlyBreakdown": {
          "00": {
            "errors": 1,
            "warnings": 3,
            "records": 5
          },
          "01": {
            "errors": 1,
            "warnings": 1,
            "records": 5
          },
          "02": {
            "errors": 2,
            "warnings": 3,
            "records": 5
          },
          "03": {
            "errors": 3,
            "warnings": 2,
            "records": 7
          },
    …
    …
        "generatedAt": "2025-10-08T05:19:05.603889"
      }
    }

    The output of the Step Functions state machine shows the daily summary insights of the log files created by the Lambda function.

Clean up

To avoid costs, remove all resources created for this post once you’re done. Run the following command after replacing amzn-s3-demo-bucket1 with your own bucket name to delete the resources you deployed for this post’s solution:

aws s3 rm s3://amzn-s3-demo-bucket1 --recursive
sam delete
rm -rf logs/

Conclusion

In this post, you learned how AWS Step Functions Distributed Map can use prefix-based iteration with LOAD_AND_FLATTEN transformation to read and process multiple data objects from Amazon S3 buckets directly. You no longer need one step to process object metadata and another to load the data objects. Loading and flatting in one step is particularly valuable for data processing pipelines, batch operations, and event-driven architectures where objects are continually added to S3 locations. By eliminating the need to maintain object manifests, you can build more resilient, dynamic data processing workflows with less code and fewer moving parts.

New input sources for Distributed Map are available in all commercial AWS Regions where AWS Step Functions is available. To get started, you can use the Distributed Map mode today in the AWS Step Functions console. To learn more, visit the Step Functions developer guide.

For more serverless learning resources, visit Serverless Land.

Introducing AWS RTB Fabric for real-time advertising technology workloads

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/introducing-aws-rtb-fabric-for-real-time-advertising-technology-workloads/

Today, we’re announcing AWS RTB Fabric, a fully managed service purpose built for real-time bidding (RTB) advertising workloads. The service helps advertising technology (AdTech) companies seamlessly connect with their supply and demand partners, such as Amazon Ads, GumGum, Kargo, MobileFuse, Sovrn, TripleLift, Viant, Yieldmo and more, to run high-volume, latency-sensitive RTB workloads on Amazon Web Services (AWS) with consistent single-digit millisecond performance and up to 80% lower networking costs compared to standard networking costs.

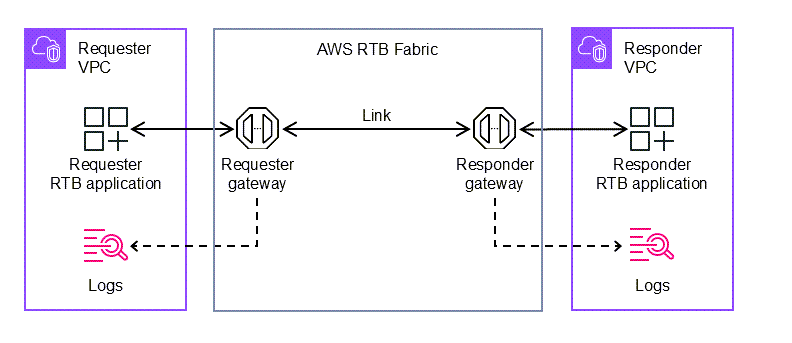
AWS RTB Fabric provides a dedicated, high-performance network environment for RTB workloads and partner integrations without requiring colocated, on-premises infrastructure or upfront commitments. The following diagram shows the high-level architecture of RTB Fabric.

AWS RTB Fabric also includes modules, a capability that helps customers bring their own and partner applications securely into the compute environment used for real-time bidding. Modules support containerized applications and foundation models (FMs) that can enhance transaction efficiency and bidding effectiveness. At launch, AWS RTB Fabric includes modules for optimizing traffic management, improving bid efficiency, and increasing bid response rates, all running inline within the service for consistent low-latency execution.

The growth of programmatic advertising has created a need for low-latency, cost-efficient infrastructure to support RTB workloads. AdTech companies process millions of bid requests per second across publishers, supply-side platforms (SSPs), and demand-side platforms (DSPs). These workloads are highly sensitive to latency because most RTB auctions must complete within 200–300 milliseconds and require reliable, high-speed exchange of OpenRTB requests and responses among multiple partners. Many companies have addressed this by deploying infrastructure in colocation data centers near key partners, which reduces latency but adds operational complexity, long provisioning cycles, and high costs. Others have turned to cloud infrastructure to gain elasticity and scale, but they often face complex provisioning, partner-specific connectivity, and long-term commitments to achieve cost efficiency. These gaps add operational overhead and limit agility. AWS RTB Fabric solves these challenges by providing a managed private network built for RTB workloads that delivers consistent performance, simplifies partner onboarding, and achieves predictable cost efficiency without the burden of maintaining colocation or custom networking setups.

Key capabilities
AWS RTB Fabric introduces a managed foundation for running RTB workloads at scale. The service provides the following key capabilities:

  • Simplified connectivity to AdTech partners – When you register an RTB Fabric gateway, the service automatically generates secure endpoints that can be shared with selected partners. Using the AWS RTB Fabric API, you can create optimized, private connections to exchange RTB traffic securely across different environments. External Links are also available to connect with partners who aren’t using RTB Fabric, such as those operating on premises or in third-party cloud environments. This approach shortens integration time and simplifies collaboration among AdTech participants.
  • Dedicated network for low-latency advertising transactions – AWS RTB Fabric provides a managed, high-performance network layer optimized for OpenRTB communication. It connects AdTech participants such as SSPs, DSPs, and publishers through private, high-speed links that deliver consistent single-digit millisecond latency. The service automatically optimizes routing paths to maintain predictable performance and reduce networking costs, without requiring manual peering or configuration.
  • Pricing model aligned with RTB economics – AWS RTB Fabric uses a transaction-based pricing model designed to align with programmatic advertising economics. Customers are billed per billion transactions, providing predictable infrastructure costs that align with how advertising exchanges, SSPs, and DSPs operate.
  • Built-in traffic management modules – AWS RTB Fabric includes configurable modules that help AdTech workloads operate efficiently and reliably. Modules such as Rate Limiter, OpenRTB Filter, and Error Masking help you control request volume, validate message formats, and manage response handling directly in the network path. These modules execute inline within the AWS RTB Fabric environment, maintaining network-speed performance without adding application-level latency. All configurations are managed through the AWS RTB Fabric API, so you can define and update rules programmatically as your workloads scale.

Getting started
Today, you can start building with AWS RTB Fabric using the AWS Management Console, AWS Command Line Interface (AWS CLI), or infrastructure-as-code (IaC) tools such as AWS CloudFormation and Terraform.

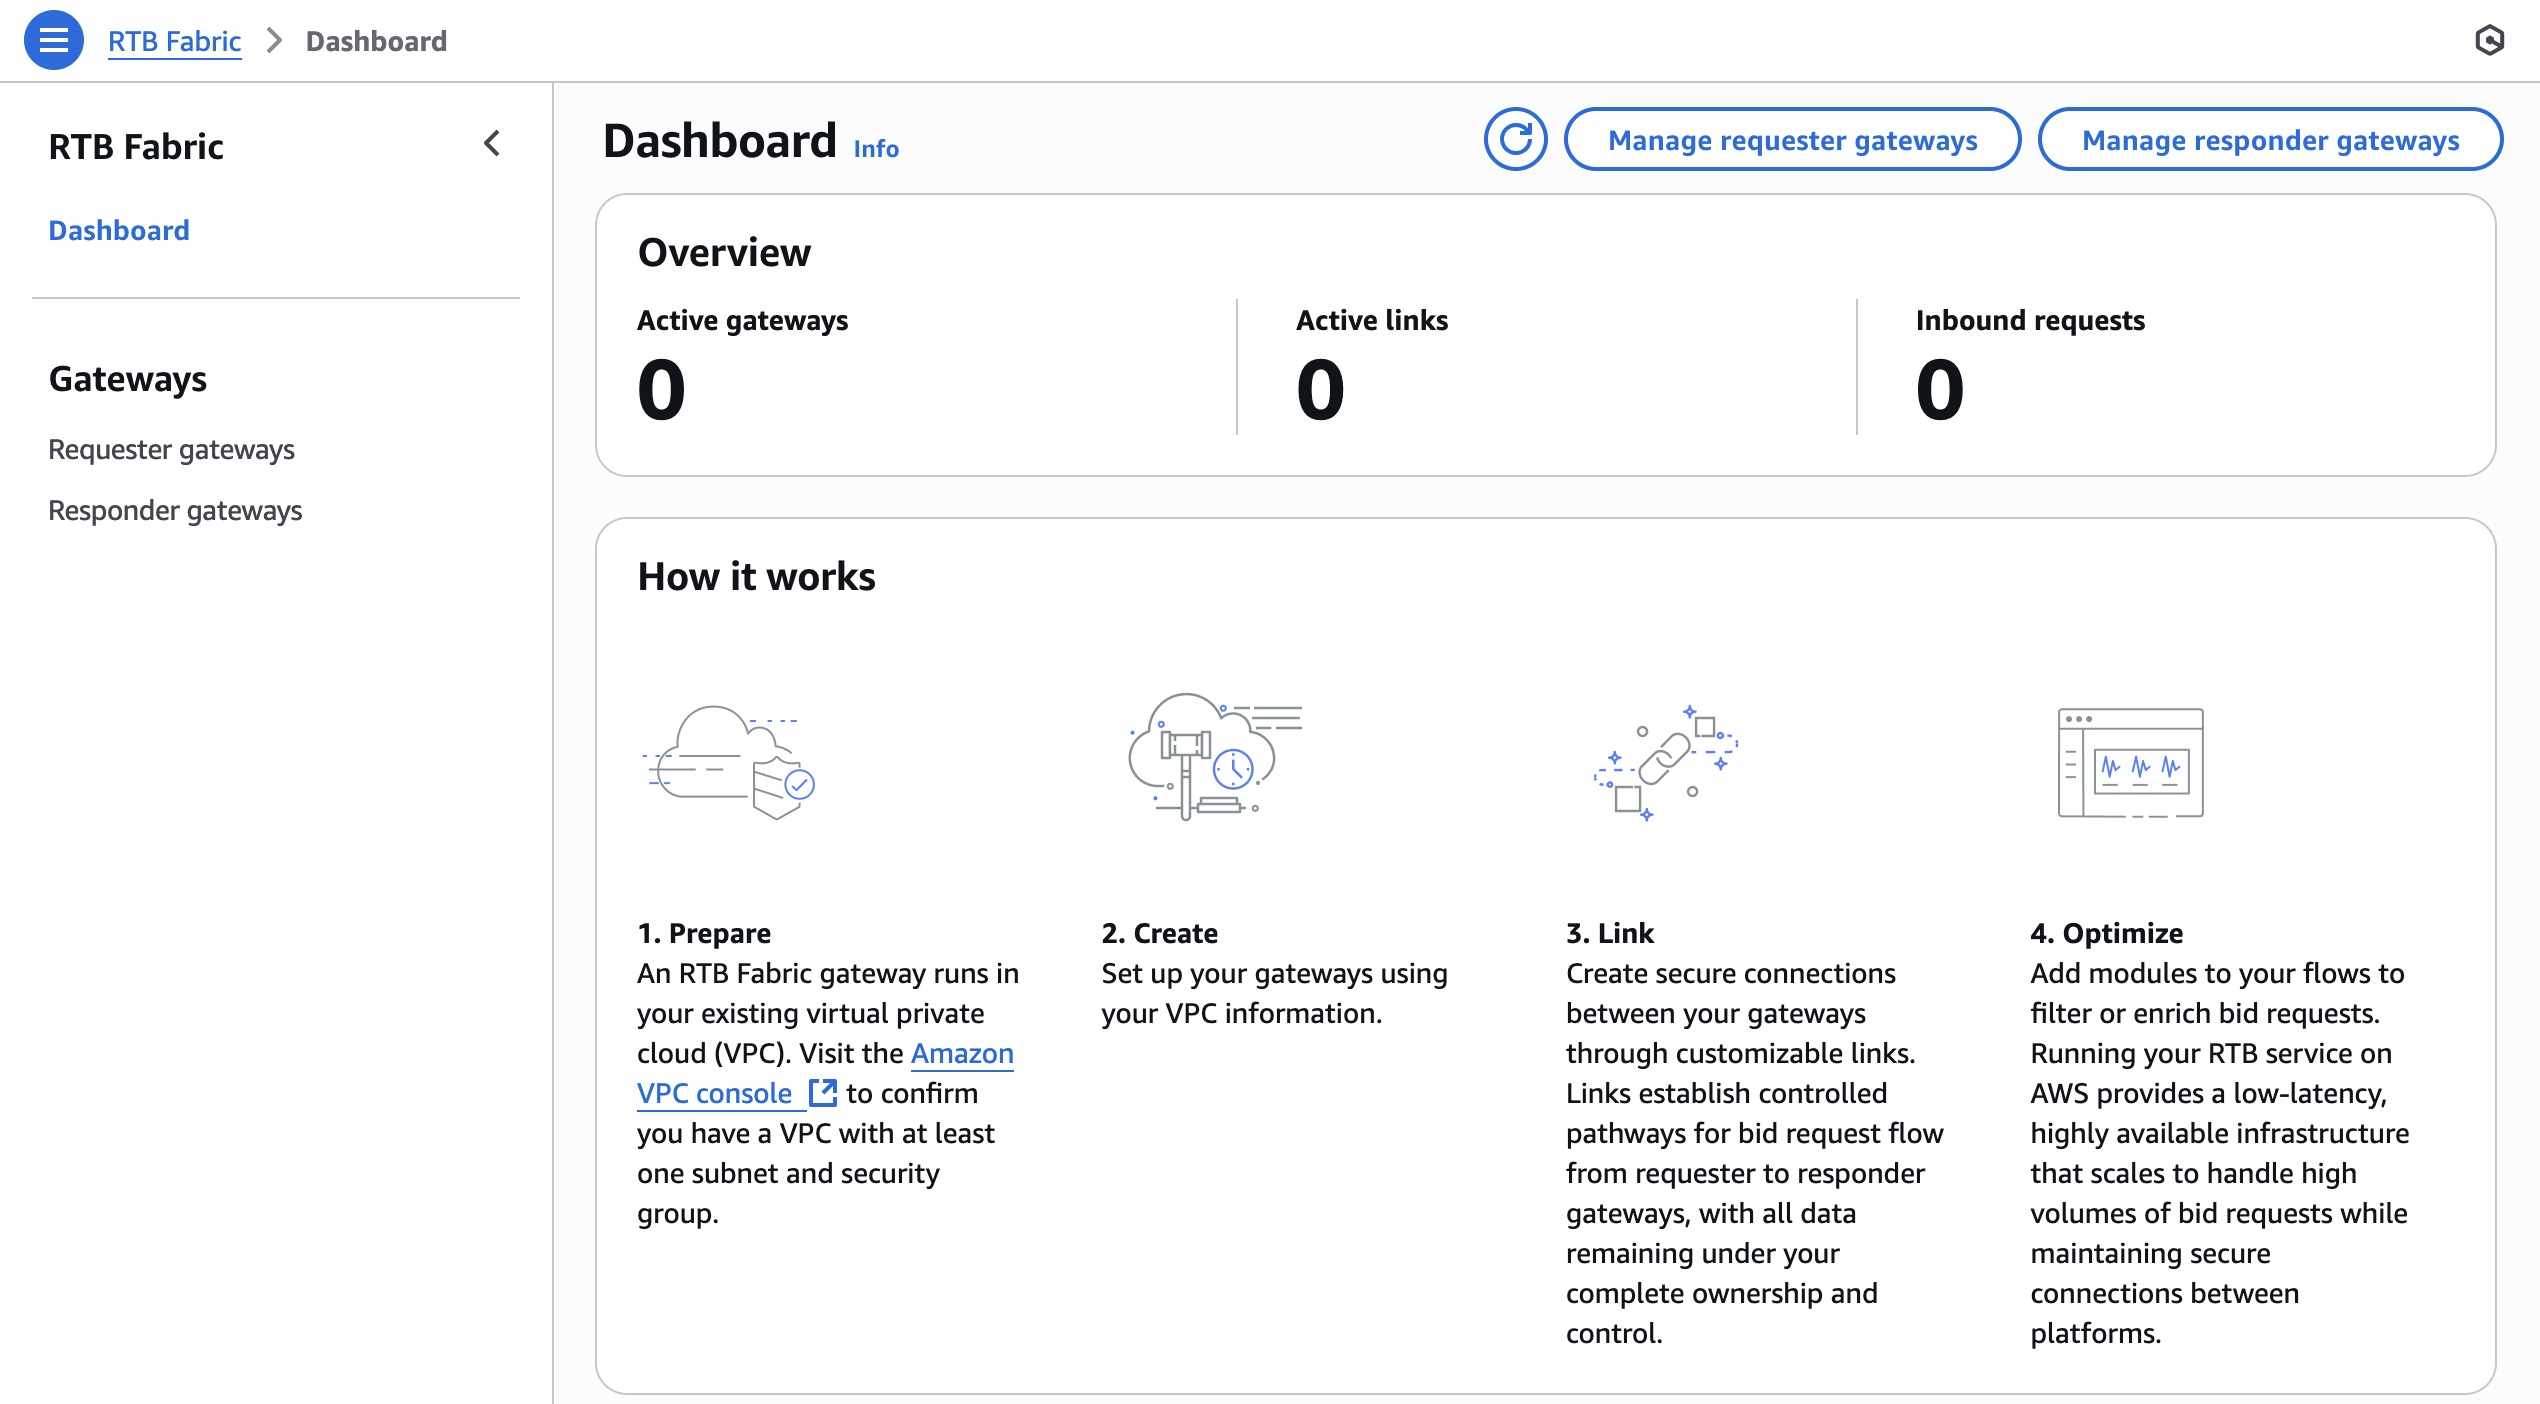
The console provides a visual entry point to view and manage RTB gateways and links, as shown on the Dashboard of the AWS RTB Fabric console.

You can also use the AWS CLI to configure gateways, create links, and manage traffic programmatically. When I started building with AWS RTB Fabric, I used the AWS CLI to configure everything from gateway creation to link setup and traffic monitoring. The setup ran inside my Amazon Virtual Private Cloud (Amazon VPC) endpoint while AWS managed the low-latency infrastructure that connected workloads.

To begin, I created a requester gateway to send bid requests and a responder gateway to receive and process bid responses. These gateways act as secure communication points within the AWS RTB Fabric.

# Create a requester gateway with required parameters
aws rtbfabric create-requester-gateway \
  --description "My RTB requester gateway" \
  --vpc-id vpc-12345678 \
  --subnet-ids subnet-abc12345 subnet-def67890 \
  --security-group-ids sg-12345678 \
  --client-token "unique-client-token-123"
# Create a responder gateway with required parameters
aws rtbfabric create-responder-gateway \
  --description "My RTB responder gateway" \
  --vpc-id vpc-01f345ad6524a6d7 \
  --subnet-ids subnet-abc12345 subnet-def67890 \
  --security-group-ids sg-12345678 \
  --dns-name responder.example.com \
  --port 443 \
  --protocol HTTPS

After both gateways were active, I created a link from the requester to the responder to establish a private, low-latency communication path for OpenRTB traffic. The link handled routing and load balancing automatically.

# Requester account creating a link from requester gateway to a responder gateway
aws rtbfabric create-link \
  --gateway-id rtb-gw-requester123 \
  --peer-gateway-id rtb-gw-responder456 \
  --log-settings '{"applicationLogs:{"sampling":"errorLog":10.0,"filterLog":10.0}}'
# Responder account accepting a link from requester gateway to responder gateway
aws rtbfabric accept-link \
  --gateway-id rtb-gw-responder456 \
  --link-id link-reqtoresplink789 \
  --log-settings '{"applicationLogs:{"sampling":"errorLog":10.0,"filterLog":10.0}}'

I also connected with external partners using External Links, which extended my RTB workloads to on-premises or third-party environments while maintaining the same latency and security characteristics.

# Create an inbound external link endpoint for an external partner to send bid requests to
aws rtbfabric create-inbound-external-link \
  --gateway-id rtb-gw-responder456
# Create an outbound external link for sending bid requests to an external partner
aws rtbfabric create-outbound-external-link \
  --gateway-id rtb-gw-requester123 \
  --public-endpoint "https://my-external-partner-responder.com"

To manage traffic efficiently, I added modules directly into the data path. The Rate Limiter module controlled request volume, and the OpenRTB Filter validated message formats inline at network speed.

# Attach a rate limiting module
aws rtbfabric update-link-module-flow \
  --gateway-id rtb-gw-responder456 \
  --link-id link-toresponder789 \
  --modules '{"name":"RateLimiter":"moduleParameters":{"rateLimiter":{"tps":10000}}}'

Finally, I used Amazon CloudWatch to monitor throughput, latency, and module performance, and I exported logs to Amazon Simple Storage Service (Amazon S3) for auditing and optimization.

All configurations can also be automated with AWS CloudFormation or Terraform, allowing consistent, repeatable deployment across multiple environments. With RTB Fabric, I could focus on optimizing bidding logic while AWS maintained predictable, single-digit millisecond performance across my AdTech partners.

For more details, refer to the AWS RTB Fabric User Guide.

Now available
AWS RTB Fabric is available today in the following AWS Regions: US East (N. Virginia), US West (Oregon), Asia Pacific (Singapore), Asia Pacific (Tokyo), Europe (Frankfurt), and Europe (Ireland).

AWS RTB Fabric is continually evolving to address the changing needs of the AdTech industry. The service expands its capabilities to support secure integration of advanced applications and AI-driven optimizations in real-time bidding workflows that help customers simplify operations and improve performance on AWS. To learn more about AWS RTB Fabric, visit the AWS RTB Fabric page.

– Betty

The attendee guide to digital sovereignty sessions at AWS re:Invent 2025

Post Syndicated from Brittany Bunch original https://aws.amazon.com/blogs/security/the-attendee-guide-to-digital-sovereignty-sessions-at-aws-reinvent-2025/

AWS re:Invent 2025, the premier cloud computing conference hosted by Amazon Web Services (AWS), returns to Las Vegas, Nevada, from December 1–5, 2025. This flagship event brings together the global cloud community for an immersive week of learning, collaboration, and innovation across multiple venues. Whether you’re a cloud expert, business leader, or technology enthusiast, re:Invent offers unparalleled opportunities to explore cutting-edge cloud solutions, engage with AWS experts, and build valuable connections with peers from around the world.

From technical deep dives to strategic business sessions, re:Invent 2025 is your gateway to understanding and using the most advanced cloud technologies. In the Expo, you can visit the Digital Sovereignty and Hybrid Cloud kiosks in the AWS Village to learn about the upcoming AWS European Sovereign Cloud and other digital sovereignty solutions, and get your questions answered by AWS experts.

Join us to discover the latest cloud industry innovations, gain deep technical insights, and learn how to optimize your cloud investments for digital sovereignty. Sessions this year will include comprehensive coverage of the AWS sovereign-by-design approach, including the enhanced security capabilities of the AWS Nitro System, our expanding portfolio of digital sovereignty solutions, and the latest developments of the AWS European Sovereign Cloud. With the growing momentum around digital sovereignty, explore how AWS continues to innovate with sovereign cloud solutions that help customers maintain control over their data while using the full power of the cloud. You can customize your learning path by reserving session seating now by signing in to your attendee portal or the AWS Events mobile app.

Breakout sessions and code talks

To add sessions to your AWS re:Invent agenda and find time and location information, choose the session title link.

Security track

SEC201 | Breakout | AWS European Sovereign Cloud: From concept to reality
Colm MacCárthaigh, VP/Distinguished Engineer – EC2 Networking, AWS Addy Upreti, Principal Technical Product Manager – EC2 Core Product Management, AWS
Get a firsthand look at the AWS European Sovereign Cloud. Explore this new, independent infrastructure’s dedicated architecture, EU-based operations, operational controls coupled with governance and legal framework that powers this cloud. Learn how this cloud solution is built, operated, and secured entirely within Europe.

Cloud operations track

COP409 | Code Talk | Building Sovereign Cloud Environments
Bo Lechangeur, Pr. Delivery Engineer – STCE, AWS, and Randy Domingo, Sr. Software Development Manager – STCE, AWS
As organizations scale their operations globally, they need to meet evolving data residency, security, compliance, and business continuity requirements. This session explores how AWS Control Tower and Landing Zone Accelerator on AWS support key sovereignty requirements, including country-specific compliance frameworks, regional service selection, automated controls for data movement, and cross-border transfers. Through real-world examples, the session demonstrates how organizations can leverage AWS to implement country-specific security controls, maintain operational consistency across multi-region deployments, accelerate cloud compliance, and deploy automated security and compliance at scale.

Hybrid cloud and multicloud track

HMC202 | Breakout | AWS wherever you need it: From the cloud to the edge
Speakers: Spencer Dillard, Director, Software Development – EC2 Edge, AWS, Madhura Kale, Senior Manager, Technical Product Management – EC2 Core, AWS
While most workloads can be migrated to the cloud, some remain on-premises or at the edge due to low latency, local data processing, or digital sovereignty needs. In this session, learn how AWS services like AWS Outposts, AWS Local Zones, AWS Dedicated Local Zones, and AWS IoT support hybrid cloud and edge computing workloads such as multiplayer gaming, high-frequency trading, medical imaging, smart manufacturing, and generative AI applications with data residency requirements.

HMC308 | Breakout | Build generative and agentic AI applications on-premises and at the edge
Speakers: Chris McEvilly, Senior Solutions Architect – Hybrid Edge, AWS, Pranav Chachra, Principal Technical Product Manager – EC2 Core, AWS, and Fernando Galves, Senior Solutions Architect – Generative AI, AWS
As customers scale generative AI and agentic AI implementations from pilots to production, they need to balance speed of innovation with data sovereignty requirements, low-latency edge processing needs, and space, power, and cost efficiency. This session explores how to build generative and agentic AI solutions using AWS Local Zones, AWS Outposts, and AWS Dedicated Local Zones. Discover architectural patterns and best practices for deploying foundation models across distributed locations. Learn how to implement Retrieval Augmented Generation (RAG) with locally stored data. Gain insights into strategies for model selection and optimization.

HMC310 | Breakout | Digital sovereignty and data residency with AWS Hybrid and Edge services
Speakers: Mallory Gershenfeld, Senior Technical Product Manager – S3, AWS, Ben Lavasani, Senior Specialist – Hybrid and Edge, AWS, and Majd Aldeen Masriah, Director of Enterprise – Architecture, Geida
Countries around the world are increasingly introducing or updating data residency and digital sovereignty laws that require at least one copy, or sometimes all data, to be stored or processed in a specific geographic or sovereign location that introduces new challenges for customers. This session explores how AWS services, including AWS Dedicated Local Zones, AWS Local Zones, and AWS Outposts can help you with your digital sovereignty use cases. We’ll examine best practices for data residency, security controls, and operational consistency across deployments at the edge.

Interactive sessions (chalk talks and workshops)

Security track

SEC301| Chalk Talk | Architecting for Digital Sovereignty: From Foundation to Practice
Speakers: Eric Rose, Principal Security SA – Global Services Security, AWS and Armin Schneider, Digital Sovereignty Specialist SA – Global Services Security Digital Sovereignty
Join this chalk talk that bridges security fundamentals with practical architecture strategies for implementing digital sovereignty in the cloud. Through real-world examples from the United Arab Emirates Cybersecurity Council and the upcoming AWS European Sovereign Cloud, we’ll explore how organizations can use AWS sovereignty features effectively. We’ll cover practical architectural patterns for data residency, operational control, and security measures that help customers maintain full control of their data. Perfect for cloud architects and security teams, this session will show you how to design solutions that balance sovereignty requirements with cloud advantages, illustrated with examples from government and enterprise deployments.

Hybrid cloud and multicloud track

HMC301| Workshop | Build and operate resilient and performant distributed applications
Speakers: Saravanan Shanmugam, Senior Solutions Architect – Hybrid Edge, AWS and Sedji Gaouaou, Senior Solutions Architect – Networking, AWS
This workshop explores how to design and implement applications for multi-geo operations while meeting data residency and performance requirements. You will learn how to design fault-tolerant, latency-sensitive applications across distributed locations with limited hardware resources. You will also explore distributed hybrid architectures, edge networking implementations, and traffic management solutions that balance regulatory requirements with high availability needs. Learn practical strategies for optimizing performance while maintaining data sovereignty across distributed locations.

HMC302| Workshop| Implementing agentic AI solutions on-premises and at the edge
Speakers: Fernando Galves, Senior Solutions Architect – Generative AI, AWS and Kyle Palasti, Senior Solutions Architect – Hybrid Edge, AWS
As governments and standards bodies develop data protection and privacy regulations, organizations increasingly need to combine the use of generative AI tooling in the cloud with regulated data that needs to remain on-premises to meet data residency requirements. In this workshop, learn how to extend Amazon Bedrock AgentCore to hybrid and edge services like AWS Outposts and AWS Local Zones to build distributed agentic applications using Model Context Protocol (MCP) and agent-to-agent (A2A) communication with on-premises data for improved model outcomes. Get hands-on with hybrid agentic AI using Amazon Bedrock and Strands Agents while exploring AWS hybrid and edge services.

HMC305 | Workshop | Low-latency SLM deployment: Optimizing inference on AWS Hybrid and Edge Services
Speakers: Leonardo Solano, Principal Solutions Architect – Networking & Hybrid Edge, AWS and Obed Gutierrez, Senior Solutions Architect, AWS
This hands-on workshop demonstrates a fully local deployment approach for running Small Language Models (SLMs) at the edge using AWS Local Zones and AWS Outposts. The implementation focuses on achieving low-latency inference and enabling data sovereignty compliance through Retrieval Augmented Generation (RAG) applications within local infrastructure. Using Amazon Elastic Compute Cloud (Amazon EC2) instances and publicly available models, you will learn how to deploy, optimize, and manage SLMs in edge environments, ensuring the RAG system and language model operate locally to meet strict latency and data residency requirements for production scenarios.

HMC312 | Chalk Talk | Implement RAG while meeting data residency requirements
Speakers: Lakshmi VP, Solutions Architect, AWS and Akshata Ketkar, Senior Product Manager – EC2 Edge, AWS
As governments develop data protection and privacy regulations, organizations increasingly need to leverage generative AI with regulated data that needs to remain on-premises to meet data sovereignty requirements. This session explores how to implement Retrieval Augmented Generation (RAG) with on-premises and edge data. Learn how to extend Amazon Bedrock AgentCore to AWS Outposts and AWS Local Zones for a hybrid RAG architecture, or build a local RAG architecture for more stringent data residency requirements. Discover the latest techniques like reranker models to improve precision without increasing model size, reduce inference cost, and enforce more governance and control over prompt outcomes.

HMC314 | Chalk Talk | Deploying for resilience: HA/DR strategies for AWS Outposts and Local Zones
Speakers: Afaq Khan, Senior Product Manager – EC2 Edge, AWS and Brianna Rosentrater, Senior Solutions Architect – Hybrid Edge, AWS
Critical workloads at the edge demand robust high-availability and disaster recovery strategies. In this chalk talk, learn how to plan and implement resilient deployments using AWS hybrid cloud and edge computing services. We’ll examine how to architect edge infrastructure using AWS Local Zones and AWS Outposts, covering key aspects of networking, compute, and storage redundancy. Through real customer examples and reference architectures, we’ll explore deployment patterns and best practices for maintaining business continuity across failure modes. Join us to learn practical strategies for achieving your RPO/RTO objectives with edge deployments.

HMC403 | Code Talk | Build and optimize edge architects for resiliency with AI
Speakers: Jesus Federico, Principal Solutions Architect – Generative AI, AWS and Robert Belson, Senior Solutions Architect & Developer Advocate, AWS
This live coding session explores how to automate edge infrastructure operations with AI. Discover how to build truly resilient architectures with the latest AWS Outposts and AWS Local Zones APIs. We’ll walk through real-world code examples for querying Outposts hardware inventory, implementing intelligent resource placement, and automating failover configurations. You’ll learn how Amazon Bedrock can analyze architecture patterns and generate Infrastructure as Code (IaC) recommendations for optimal component distribution. Walk away with practical techniques for API integration, automated health checks, and dynamic resource allocation, plus working code samples and deployment templates for building adaptive, highly available edge solutions.

HMC316 | Chalk Talk | Address digital sovereignty with hybrid cloud solutions
Speakers: Sherry Lin, Principal Product Manager – EC2 Core, AWS and Enrico Liguori, Solutions Architect – Networking, AWS
As organizations scale innovative solutions globally, they need to navigate complex digital sovereignty requirements. This session explores how AWS can help you accelerate global scaling while meeting regulatory obligations. We’ll compare various sovereign infrastructure options with a focus on AWS Local Zones, AWS Dedicated Local Zones, AWS Outposts, and AWS European Sovereign Cloud. Learn how to choose the best option for your sovereign needs and architect applications for data residency and resiliency. Discover how to implement security controls to regulate how data can be stored, processed, and transferred, and how to prevent unauthorized data access.


For a full view of digital sovereignty content, including sessions with partners, explore the AWS re:Invent catalog and filter on the Digital Sovereignty area of interest. Not able to attend in-person? Register forthe virtual-only pass offered at no additional cost to livestream keynotes and innovation talks, and access on-demand breakout sessions today. See you in Las Vegas or on the livestream!

If you have feedback about this post, submit comments in the Comments section below.

Brittany Bunch

Brittany Bunch

Brittany is a Product Marketing Manager on the AWS Security Marketing team based in Atlanta. She focuses on digital sovereignty and brings over a decade of experience in brand marketing, including employer branding at Amazon. Prior to AWS, she led brand marketing initiatives at several large enterprise companies.

Introducing Amazon EBS Volume Clones: Create instant copies of your EBS volumes

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/introducing-amazon-ebs-volume-clones-create-instant-copies-of-your-ebs-volumes/


As someone that used to work at Sun Microsystems, where ZFS was invented, I’ve always loved working with storage systems that offer instant volume copies for my development and testing needs.

Today, I’m excited to share that AWS is bringing similar capabilities to Amazon Elastic Block Store (Amazon EBS) with the launch of Amazon EBS Volume Clones, a new capability that lets you create instant point-in-time copies of your EBS volumes within the same Availability Zone.

Many customers need to create copies of their production data to support development and testing activities in a separate nonproduction environment. Until now, this process required taking an EBS snapshot (stored in Amazon Simple Storage Service (Amazon S3)) and then creating a new volume from that snapshot. Although this approach works, the process creates operational overhead due to multiple steps.

With Amazon EBS Volume Clones, you can now create copies of your EBS volumes with a single API call or console click. The copied volumes are available within seconds and provide immediate access to your data with single-digit millisecond latency. This makes Volume Clones particularly useful for quickly setting up test environments with production data or creating temporary copies of databases for development purposes.

Let me show you how Volume Clones works
For this post, I created a small Amazon Elastic Compute Cloud (Amazon EC2) instance, with an attached volume. I created a file on the root file system with the command echo "Hello CopyVolumes" > hello.txt.

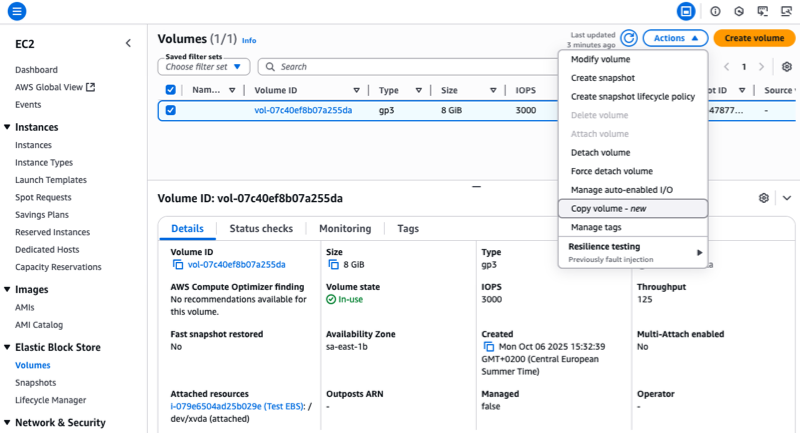
To initiate the copy, I open a browser on the AWS Management Console and I navigate to EC2, Elastic Block Store, Volumes. I select the volume I want to copy.

Note that, at the time of publication of this post, only encrypted volumes can be copied.

On the Actions menu, I choose the Copy Volume option.

Copy Volume - initiate

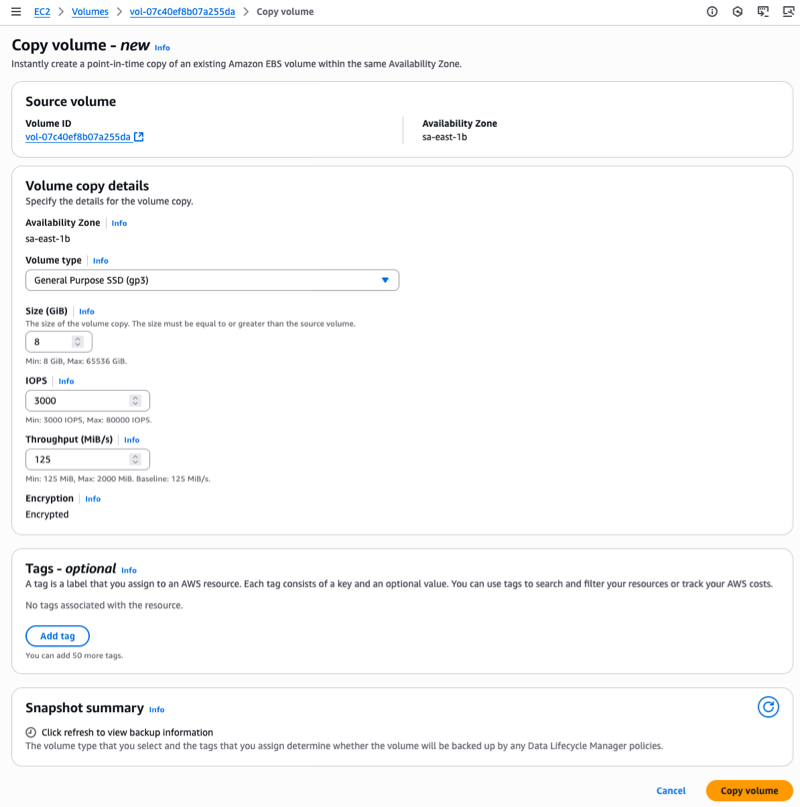
Next, I choose the details of the target volume. I can change the Volume type and adjust the Size, IOPS, and Throughput parameters. I choose Copy volume to start the Volume Clone operation.

Copy Volume - Parameters

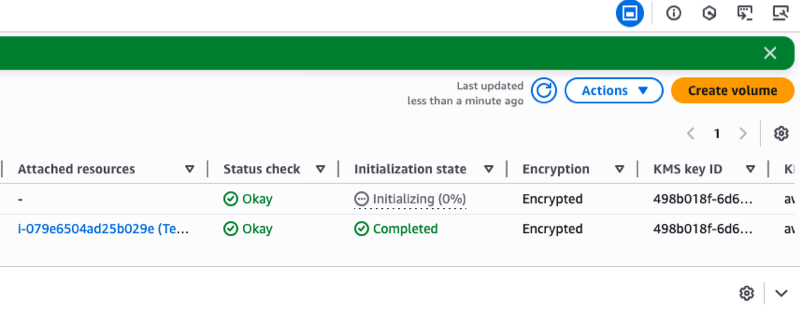
The copied volume enters the Creating state and becomes available within seconds. I can then attach it to an EC2 instance and start using it immediately.

Data blocks are copied from the source volume and written to the volume copy in the background. The volume remains in the Initializing state until the process is complete. I can monitor its progress with the describe-volume-status API. The initializing operation doesn’t affect the performance of the source volume. I can continue using it normally during the copy process.

I love that the copied volume is available immediately. I don’t need to wait for its initialization to complete. During the initialization phase, my copied volume delivers performance based on the lowest of: a baseline of 3,000 IOPS and 125 MiB/s, the source volume’s provisioned performance, or the copied volume’s provisioned performance.

After initialization is completed, the copied volume becomes fully independent of the source volume and delivers its full provisioned performance.

Copy Volume - InitializingAlternatively, I can use the AWS Command Line Interface (AWS CLI) to initiate the copy:

aws ec2 copy-volumes                          \
     --source-volume-id vol-1234567890abcdef0 \
     --size 500                               \
     --volume-type gp3

After the volume copy is created, I attach it to my EC2 instance and mount it. I can check the file I created at start is present.

First, I attach the volume from my laptop, using the attach-volume command:

aws ec2 attach-volume \
         --volume-id 'vol-09b700e3a23a9b4ad' \
         --instance-id 'i-079e6504ad25b029e'   \
         --device '/dev/sdb'

Then, I connect to the instance, and I type these commands:

$ sudo lsblk -f
NAME          FSTYPE FSVER LABEL UUID                                 FSAVAIL FSUSE% MOUNTPOINTS
nvme0n1                                                                              
├─nvme0n1p1   xfs          /     49e26d9d-0a9d-4667-b93e-a23d1de8eacd    6.2G    22% /
└─nvme0n1p128 vfat   FAT16       3105-2F44                               8.6M    14% /boot/efi
nvme1n1                                                                              
├─nvme1n1p1   xfs          /     49e26d9d-0a9d-4667-b93e-a23d1de8eacd                
└─nvme1n1p128 vfat   FAT16       3105-2F44     

$ sudo mount -t xfs /dev/nvme1n1p1 /data

$ df -h
Filesystem        Size  Used Avail Use% Mounted on
devtmpfs          4.0M     0  4.0M   0% /dev
tmpfs             924M     0  924M   0% /dev/shm
tmpfs             370M  476K  369M   1% /run
/dev/nvme0n1p1    8.0G  1.8G  6.2G  22% /
tmpfs             924M     0  924M   0% /tmp
/dev/nvme0n1p128   10M  1.4M  8.7M  14% /boot/efi
tmpfs             185M     0  185M   0% /run/user/1000
/dev/nvme1n1p1    8.0G  1.8G  6.2G  22% /data

$ cat /data/home/ec2-user/hello.txt 
Hello CopyVolumes

Things to know
Volume Clones creates copies within the same Availability Zone as your source volume. You can create copies from encrypted volumes only, and the size of your copy must be equal to or greater than the source volume.

Volume Clones creates crash-consistent copies of your volumes, exactly like snapshots. For application consistency, you need to pause application I/O operations before creating the copy. For example, with PostgreSQL databases, you can use the pg_start_backup() and pg_stop_backup() functions to pause writes and create a consistent copy. At the operating system level on Linux with XFS, you can use the xfs_freeze command to temporarily suspend and resume access to the file system and ensure all cached updates are written to disk.

Although Volume Clones creates point-in-time copies, it complements rather than replaces EBS snapshots for backup purposes. EBS snapshots remain the recommended solution for data backup and protection against AZ-level and volume failures. Snapshots provide incremental backups to Amazon S3 with 11 nines of durability, compared to Volume Clones which maintains EBS volume durability (99.999% for io2, 99.9% for other volume types). Consider using Volume Clones specifically for test and development environment scenarios where you need instant access to volume copies.

Copied volumes exist independently of their source volumes and continue to incur standard EBS volume charges until you delete them. To manage costs effectively, implement governance rules to identify and remove copied volumes that are no longer needed for your development or testing activities.

Pricing and availability
Volume Clones supports all EBS volume types and works with volumes in the same AWS account and Availability Zone. This new capability is available in all AWS commercial Regions, selected Local Zones, and in the AWS GovCloud (US).

For pricing, you’re charged a one-time fee per GiB of data on the source volume at initiation and standard EBS pricing for the new volume.

I find Volume Clones particularly valuable for database workloads and continuous integration (CI) scenarios. For instance, you can quickly create a copy of your production database for testing new features or troubleshooting issues without impacting your production environment or waiting for data to hydrate from Amazon S3.

To get started with Amazon EBS Volume Clones, visit the Amazon EBS section on the console or check out the EBS documentation. I look forward to hearing how you use this capability to improve your development workflows.

— seb

AWS Weekly Roundup: Amazon Quick Suite, Amazon EC2, Amazon EKS, and more (October 13, 2025)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-quick-suite-amazon-ec2-amazon-eks-and-more-october-13-2025/
This week I was at the inaugural AWS AI in Practice meetup from the AWS User Group UK. AI-assisted software development and agents were the focus of the evening! Next week I’ll be in Italy for Codemotion (Milan) and an AWS User Group meetup (Rome). I am also excited to try the new Amazon Quick Suite that brings AI-powered research, business intelligence, and automation capabilities into a single workspace.

Last week’s launches
Here are the launches that got my attention this week:

Additional updates
Here are some additional projects, blog posts, and news items that I found interesting:

Upcoming AWS events
Check your calendars so that you can sign up for these upcoming events:

  • AWS AI Agent Global Hackathon – This is your chance to dive deep into our powerful generative AI stack and create something truly awesome. From September 8th to October 20th, you have the opportunity to create AI agents using AWS suite of AI services, competing for over $45,000 in prizes and exclusive go-to-market opportunities.
  • AWS Gen AI Lofts – You can learn AWS AI products and services with exclusive sessions, meet industry-leading experts, and have valuable networking opportunities with investors and peers. Register in your nearest city: Paris (October 7–21), London (Oct 13–21), and Tel Aviv (November 11–19).
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Budapest (October 16).

Join the AWS Builder Center to learn, build, and connect with builders in the AWS community. Browse here upcoming in-person events, developer-focused events, and events for startups.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Danilo
Announcing Amazon Quick Suite: your agentic teammate for answering questions and taking action

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/reimagine-the-way-you-work-with-ai-agents-in-amazon-quick-suite/

Today, we’re announcing Amazon Quick Suite, a new agentic teammate that quickly answers your questions at work and turns those insights into actions for you. Instead of switching between multiple applications to gather data, find important signals and trends, and complete manual tasks, Quick Suite brings AI-powered research, business intelligence, and automation capabilities into a single workspace. You can now analyze data through natural language queries, find critical information across enterprise and external sources in minutes, and automate processes from simple tasks to complex multi-department workflows.

Here’s a look into Quick Suite.

Business users often need to gather data across multiple applications—pulling customer details, checking performance metrics, reviewing internal product information, and performing competitive intelligence. This fragmented process often requires consultation with specialized teams to analyze advanced datasets, and in some cases, must be repeated regularly, reducing efficiency and leading to incomplete insights for decision-making.

Quick Suite helps you overcome these challenges by combining agentic teammates for research, business intelligence, and automation into a unified digital workspace for your day-to-day work.

Integrated capabilities that power productivity 
Quick Suite includes the following integrated capabilities:

  • Research – Quick Research accelerates complex research by combining enterprise knowledge, premium third-party data, and data from the internet for more comprehensive insights.
  • Business intelligence – Quick Sight provides AI-powered business intelligence capabilities that transform data into actionable insights through natural language queries and interactive visualizations, helping everyone make faster decisions and achieve better business outcomes.
  • Automation – Quick Flows and Quick Automate help users and technical teams to automate any business process from simple, routine tasks to complex multi-department workflows, enabling faster execution and reducing manual work across the organization.

Let’s dive into some of these key capabilities.

Quick Index: Your unified knowledge foundation
Quick Index creates a secure, searchable repository that consolidates documents, files, and application data to power AI-driven insights and responses across your organization.

As a foundational component of Quick Suite, Quick Index operates in the background to bring together all your data—from databases and data warehouses to documents and email. This creates a single, intelligent knowledge base that makes AI responses more accurate and reduces time spent searching for information.

Quick Index automatically indexes and prepares any uploaded files or unstructured data you add to your Quick Suite, enabling efficient searching, sorting, and data access. For example, when you search for a specific project update, Quick Index instantly returns results from uploaded documents, meeting notes, project files, and reference materials—all from one unified search instead of checking different repositories and file systems.

To learn more, visit the Quick Index overview page.

Quick Research: From complex business challenges to expert-level insights
Quick Research is a powerful agent that conducts comprehensive research across your enterprise data and external sources to deliver contextualized, actionable insights in minutes or hours — work that previously could take longer.

Quick Research systematically breaks down complex questions into organized research plans. Starting with a simple prompt, it automatically creates detailed research frameworks that outline the approach and data sources needed for comprehensive analysis.

After Quick Research creates the plan, you can easily refine it through natural language conversations. When you are happy with the plan, it works in the background to gather information from multiple sources, using advanced reasoning to validate findings and provide thorough analysis with citations.

Quick Research integrates with your enterprise data connected to Quick Suite, the unified knowledge foundation that connects to your dashboards, documents, databases, and external sources, including Amazon S3, Snowflake, Google Drive, and Microsoft SharePoint. Quick Research grounds key insights to original sources and reveals clear reasoning paths, helping you verify accuracy, understand the logic behind recommendations, and present findings with confidence. You can trace findings back to their original sources and validate conclusions through source citations. This makes it ideal for complex topics requiring in-depth analysis.

To learn more, visit the Quick Research overview page.

Quick Sight: AI-powered business intelligence
Quick Sight provides AI-powered business intelligence capabilities that transform data into actionable insights through natural language queries and interactive visualizations.

You can create dashboards and executive summaries using conversational prompts, reducing dashboard development time while making advanced analytics accessible without specialized skills.

Quick Sight helps you ask questions about your data in natural language and receive instant visualizations, executive summaries, and insights. This generative AI integration provides you with answers from your dashboards and datasets without requiring technical expertise.

Using the scenarios capability, you can perform what-if analysis in natural language with step-by-step guidance, exploring complex business scenarios and finding answers faster than before.

Additionally, you can respond to insights with one-click actions by creating tickets, sending alerts, updating records, or triggering automated workflows directly from your dashboards without switching applications.

To learn more, visit Quick Sight overview page.

Quick Flows: Automation for everyone
With Quick Flows, any user can automate repetitive tasks by describing their workflow using natural language without requiring any technical knowledge. Quick Flows fetches information from internal and external sources, takes action in business applications, generates content, and handles process-specific requirements.

Starting with straightforward business requirements, it creates a multi-step flow including input steps for gathering information, reasoning groups for AI-powered processing, and output steps for generating and presenting results.

After the flow is configured, you can share it with a single click to your coworkers and other teams. To execute the flow, users can open it from the library or invoke it from chat, provide the necessary inputs, and then chat with the agent to refine the outputs and further customize the results.

To learn more, visit the Quick Flows overview page.

Quick Automate: Enterprise-scale process automation
Quick Automate helps technical teams build and deploy sophisticated automation for complex, multistep processes that span departments, systems, and third-party integrations. Using AI-powered natural language processing, Quick Automate transforms complex business processes into multi-agent workflows that can be created merely by describing what you want to automate or uploading process documentation.

While Quick Flows handles straightforward workflows, Quick Automate is designed for comprehensive and complex business processes like customer onboarding, procurement automations, or compliance procedures that involve multiple approval steps, system integrations, and cross-departmental coordination. Quick Automate offers advanced orchestration capabilities with extensive monitoring, debugging, versioning, and deployment features.

Quick Automate then generates a comprehensive automation plan with detailed steps and actions. You will find a UI agent that understands natural language instructions to autonomously navigate websites, complete form inputs, extract data, and produces structured outputs for downstream automation steps.

Additionally, you can define a custom agent, complete with instructions, knowledge, and tools, to complete process-specific tasks using the visual building experience – no code required.

Quick Automate includes enterprise-grade features such as user role management and human-in-the-loop capabilities that route specific tasks to users or groups for review and approval before continuing workflows. The service provides comprehensive observability with real-time monitoring, success rate tracking, and audit trails for compliance and governance.

To learn more, visit the Quick Automate overview page.

Additional foundational capabilities
Quick Suite includes other foundational capabilities that deliver seamless data organization and contextual AI interactions across your enterprise.

Spaces – Spaces provide a straightforward way for every business user to add their own context by uploading files or connecting to specific datasets and repositories specific to their work or to a particular function. For example, you might create a space for quarterly planning that includes budget spreadsheets, market research reports, and strategic planning documents. Or you could set up a product launch space that connects to your project management system and customer feedback databases. Spaces can scale from personal use to enterprise-wide deployment while maintaining access permissions and seamless integration with Quick Suite capabilities.

Chat agents – Quick Suite includes insights agents that you can use to interact with your data and workflows through natural language. Quick Suite includes a built-in agent to answer questions across all of your data and custom chat agents that you can configure with specific expertise and business context. Custom chat agents can be tailored for particular departments or use cases—such as a sales agent connected to your product catalog data and pricing information stored in a space or a compliance agent configured with your regulatory requirements and actions to request approvals.

Additional things to know
If you’re an existing Amazon QuickSight customer – Amazon QuickSight customers will be upgraded to Quick Suite, a unified digital workspace that includes all your existing QuickSight business intelligence capabilities (now called “Quick Sight”) plus new agentic AI capabilities. This is an interface and capability change—your data connectivity, user access, content, security controls, user permissions, and privacy settings remain exactly the same. No data is moved, migrated, or changed.

Quick Suite offers per-user subscription-based pricing with consumption-based charges for the Quick Index and other optional features. You can find more detail on the Quick Suite pricing page.

Now available
Amazon Quick Suite gives you a set of agentic teammates that helps you get the answers you need using all your data and move instantly from answers to action so you can focus on high value activities that drive better business and customer outcomes.

Visit the getting started page to start using Amazon Quick Suite today.

Happy building
— Esra and Donnie

New AWS whitepaper: Security Overview of Amazon EKS Auto Mode

Post Syndicated from Todd Neal original https://aws.amazon.com/blogs/security/new-aws-whitepaper-security-overview-of-amazon-eks-auto-mode/

Amazon Web Services (AWS) has released a new whitepaper: Security Overview of Amazon EKS Auto Mode, providing customers with an in-depth look at the architecture, built-in security features, and capabilities of Amazon Elastic Kubernetes Service (Amazon EKS) Auto Mode.

The whitepaper covers the core security principles of Amazon EKS Auto Mode, highlighting its unique approach to managing Kubernetes clusters. This includes how AWS has reimagined node management by building on top of Amazon Elastic Compute Cloud (Amazon EC2) managed instances, which introduces a new way for customers to delegate operational control of EC2 instances to an AWS service.

Designed for cloud architects, security professionals, and Kubernetes practitioners, the whitepaper serves as a comprehensive guide to understanding the security architecture of Amazon EKS Auto Mode. It represents the AWS commitment to providing secure, manageable, and innovative Kubernetes infrastructure solutions that minimize undifferentiated heavy lifting, so that customers can focus more on application development and less on infrastructure management.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Todd Neal

Todd Neal

Todd is a Principal Software Engineer at AWS. His current focus is the Kubernetes data plane where he works to continually improve the security, reliability and robustness of Kubernetes Nodes and associated components.

AWS IAM Identity Center now supports customer-managed KMS keys for encryption at rest

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-iam-identity-center-now-supports-customer-managed-kms-keys-for-encryption-at-rest/

Starting today, you can use your own AWS Key Management Service (AWS KMS) keys to encrypt identity data, such as user and group attributes, stored in AWS IAM Identity Center organization instances.

Many organizations operating in regulated industries need complete control over encryption key management. While Identity Center already encrypts data at rest using AWS-owned keys, some customers require the ability to manage their own encryption keys for audit and compliance purposes.

With this launch, you can now use customer-managed KMS keys (CMKs) to encrypt Identity Center identity data at rest. CMKs provide you with full control over the key lifecycle, including creation, rotation, and deletion. You can configure granular access controls to keys with AWS Key Management Service (AWS KMS) key policies and IAM policies, helping to ensure that only authorized principals can access your encrypted data. At launch time, the CMK must reside in the same AWS account and Region as your IAM Identity Center instance. The integration between Identity Center and KMS provides detailed AWS CloudTrail logs for auditing key usage and helps meet regulatory compliance requirements.

Identity Center supports both single-Region and multi-Region keys to match your deployment needs. While Identity Center instances can currently only be deployed in a single Region, we recommend using multi-Region AWS KMS keys unless your company policies restrict you to single-Region keys. Multi-Region keys provide consistent key material across Regions while maintaining independent key infrastructure in each Region. This gives you more flexibility in your encryption strategy and helps future-proof your deployment.

Let’s get started
Let’s imagine I want to use a CMK to encrypt the identity data of my Identity Center organization instance. My organization uses Identity Center to give employees access to AWS managed applications, such as Amazon Q Business or Amazon Athena.

As of today, some AWS managed applications cannot be used with Identity Center configured with a customer managed KMS key. See AWS managed applications that you can use with Identity Center to keep you updated with the ever evolving list of compatible applications.

The high-level process requires first to create a symmetric customer managed key (CMK) in AWS KMS. The key must be configured for encrypt and decrypt operations. Next, I configure the key policies to grant access to Identity Center, AWS managed applications, administrators, and other principals who need access the Identity Center and IAM Identity Center service APIs. Depending on your usage of Identity Center, you’ll have to define different policies for the key and IAM policies for IAM principals. The service documentation has more details to help you cover the most common use cases.

This demo is in three parts. I first create a customer managed key in AWS KMS and configure it with permissions that will authorize Identity Center and AWS managed applications to use it. Second, I update the IAM policies for the principals that will use the key from another AWS account, such as AWS applications administrators. Finally, I configure Identity Center to use the key.

Part 1: Create the key and define permissions

First, let’s create a new CMK in AWS KMS.

AWS KMW, screate key, part 1

The key must be in the same AWS Region and AWS account as the Identity Center instance. You must create the Identity Center instance and the key in the management account of your organization within AWS Organization.

I navigate to the AWS Key Management Service (AWS KMS) console in the same Region as my Identity Center instance, then I choose Create a key. This launches me into the key creation wizard.

AWS KMW, screate key, part 2

Under Step 1–Configure key, I select the key type–either Symmetric (a single key used for both encryption and decryption) or Asymmetric (a public-private key pair for encryption/decryption and signing/verification). Identity Center requires symmetric keys for encryption at rest. I select Symmetric.

For key usage, I select Encrypt and decrypt which allows the key to be used only for encrypting and decrypting data.

Under Advanced options, I select KMS – recommended for Key material origin, so AWS KMS creates and manages the key material.

For Regionality, I choose between Single-Region or Multi-Region key. I select Multi-Region key to allow key administrators to replicate the key to other Regions. As explained already, Identity Center doesn’t require this today but it helps to future-proof your configuration. Remember that you can not transform a single-Region key to a multi-Region one after its creation (but you can change the key used by Identity Center).

Then, I choose Next to proceed with additional configuration steps, such as adding labels, defining administrative permissions, setting usage permissions, and reviewing the final configuration before creating the key.

AWS KMS, screate key, part 3

Under Step 2–Add Labels, I enter an Alias name for my key and select Next.

In this demo, I am editing the key policy by adding policy statements using templates provided in the documentation. I skip Step 3 and Step 4 and navigate to Step 5–Edit key policy.

AWS KMS, screate key, part 5

Identity Center requires, at the minimum, permissions allowing Identity Center and its administrators to use the key. Therefore, I add three policy statements, the first and second authorize the administrators of the service, the third one to authorize the Identity Center service itself.

{
	"Version": "2012-10-17",
	"Id": "key-consolepolicy-3",
	"Statement": [
		{
			"Sid": "Allow_IAMIdentityCenter_Admin_to_use_the_KMS_key_via_IdentityCenter_and_IdentityStore",
			"Effect": "Allow",
			"Principal": {
				"AWS": "ARN_OF_YOUR_IDENTITY_CENTER_ADMIN_IAM_ROLE"
			},
			"Action": [
				"kms:Decrypt",
				"kms:Encrypt",
				"kms:GenerateDataKeyWithoutPlaintext"
			],
			"Resource": "*",
			"Condition": {
				"StringLike": {
					"kms:ViaService": [
						"sso.*.amazonaws.com",
						"identitystore.*.amazonaws.com"
					]
				}
			}
		},
		{
			"Sid": "Allow_IdentityCenter_admin_to_describe_the_KMS_key",
			"Effect": "Allow",
			"Principal": {
				"AWS": "ARN_OF_YOUR_IDENTITY_CENTER_ADMIN_IAM_ROLE"
			},
			"Action": "kms:DescribeKey",
			"Resource": "*"
		},
		{
			"Sid": "Allow_IdentityCenter_and_IdentityStore_to_use_the_KMS_key",
			"Effect": "Allow",
			"Principal": {
				"Service": [
					"sso.amazonaws.com",
					"identitystore.amazonaws.com"
				]
			},
			"Action": [
				"kms:Decrypt",
				"kms:ReEncryptTo",
				"kms:ReEncryptFrom",
				"kms:GenerateDataKeyWithoutPlaintext"
			],
			"Resource": "*",
            "Condition": {
    	       "StringEquals": { 
                      "aws:SourceAccount": "<Identity Center Account ID>" 
	           }
            }		
		},
		{
			"Sid": "Allow_IdentityCenter_and_IdentityStore_to_describe_the_KMS_key",
			"Effect": "Allow",
			"Principal": {
				"Service": [
					"sso.amazonaws.com",
					"identitystore.amazonaws.com"
				]
			},
			"Action": [
				"kms:DescribeKey"
			],
			"Resource": "*"
		}		
	]
}

I also have to add additional policy statements to allow my use case: the use of AWS managed applications. I add these two policy statements to authorize AWS managed applications and their administrators to use the KMS key. The document lists additional use cases and their respective policies.

{
    "Sid": "Allow_AWS_app_admins_in_the_same_AWS_organization_to_use_the_KMS_key",
    "Effect": "Allow",
    "Principal": "*",
    "Action": [
        "kms:Decrypt"
    ],
    "Resource": "*",
    "Condition": {
        "StringEquals" : {
           "aws:PrincipalOrgID": "MY_ORG_ID (format: o-xxxxxxxx)"
        },
        "StringLike": {
            "kms:ViaService": [
                "sso.*.amazonaws.com", "identitystore.*.amazonaws.com"
            ]
        }
    }
},
{
   "Sid": "Allow_managed_apps_to_use_the_KMS_Key",
   "Effect": "Allow",
   "Principal": "*",
   "Action": [
      "kms:Decrypt"
    ],
   "Resource": "*",
   "Condition": {
      "Bool": { "aws:PrincipalIsAWSService": "true" },
      "StringLike": {
         "kms:ViaService": [
             "sso.*.amazonaws.com", "identitystore.*.amazonaws.com"
         ]
      },
      "StringEquals": { "aws:SourceOrgID": "MY_ORG_ID (format: o-xxxxxxxx)" }
   }
}

You can further restrict the key usage to a specific Identity Center instance, specific application instances, or specific application administrators. The documentation contains examples of advanced key policies for your use cases.

To help protect against IAM role name changes when permission sets are recreated, use the approach described in the Custom trust policy example.

Part 2: Update IAM policies to allow use of the KMS key from another AWS account

Any IAM principal that uses the Identity Center service APIs from another AWS account, such as Identity Center delegated administrators and AWS application administrators, need an IAM policy statement that allows use of the KMS key via these APIs.

I grant permissions to access the key by creating a new policy and attaching the policy to the IAM role relevant for my use case. You can also add these statements to the existing identity-based policies of the IAM role.

To do so, after the key is created, I locate its ARN and replace the key_ARNin the template below. Then, I attach the policy to the managed application administrator IAM principal. The documentation also covers IAM policies that grants Identity Center delegated administrators permissions to access the key.

Here is an example for managed application administrators:

{
      "Sid": "Allow_app_admins_to_use_the_KMS_key_via_IdentityCenter_and_IdentityStore",
      "Effect": "Allow",
      "Action": 
        "kms:Decrypt",
      "Resource": "<key_ARN>",
      "Condition": {
        "StringLike": {
          "kms:ViaService": [
            "sso.*.amazonaws.com",
            "identitystore.*.amazonaws.com"
          ]
        }
      }
    }

The documentation shares IAM policies template for the most common use cases.

Part 3: Configure IAM Identity Center to use the key

I can configure a CMK either during the enablement of an Identity Center organization instance or on an existing instance, and I can change the encryption configuration at any time by switching between CMKs or reverting to AWS-owned keys.

Please note that an incorrect configuration of KMS key permissions can disrupt Identity Center operations and access to AWS managed applications and accounts through Identity Center. Proceed carefully to this final step and ensure you have read and understood the documentation.

After I have created and configured my CMK, I can select it under Advanced configuration when enabling Identity Center.

IDC with CMK configuration

To configure a CMK on an existing Identity Center instance using the AWS Management Console, I start by navigating to the Identity Center section of the AWS Management Console. From there, I select Settings from the navigation pane, then I select the Management tab, and select Manage encryption in the Key for encrypting IAM Identity Center data at rest section.

Change key on existing IDC

At any time, I can select another CMK from the same AWS Account, or switch back to an AWS-managed key.

After choosing Save, the key change process takes a few seconds to complete. All service functionalities continue uninterrupted during the transition. If, for whatever reasons, Identity Center can not access the new key, an error message will be returned and Identity Center will continue to use the current key, keeping your identity data encrypted with the mechanism it is already encrypted with.

CMK on IDC, select a new key

Things to keep in mind
The encryption key you create becomes a crucial component of your Identity Center. When you choose to use your own managed key to encrypt identity attributes at rest, you have to verify the following points.

  • Have you configured the necessary permissions to use the KMS key? Without proper permissions, enabling the CMK may fail or disrupt IAM Identity Center administration and AWS managed applications.
  • Have you verified that your AWS managed applications are compatible with CMK keys? For a list of compatible applications, see AWS managed applications that you can use with IAM Identity Center. Enabling CMK for Identity Center that is used by AWS managed applications incompatible with CMK will result in operational disruption for those applications. If you have incompatible applications, do not proceed.
  • Is your organization using AWS managed applications that require additional IAM role configuration to use the Identity Center and Identity Store APIs? For each such AWS managed application that’s already deployed, check the managed application’s User Guide for updated KMS key permissions for IAM Identity Centre usage and update them as instructed to prevent application disruption.
  • For brevity, the KMS key policy statements in this post omit the encryption context, which allows you to restrict the use of the KMS key to Identity Center including a specific instance. For your production scenarios, you can add a condition like this for Identity Center:
    "Condition": {
       "StringLike": {
          "kms:EncryptionContext:aws:sso:instance-arn": "${identity_center_arn}",
          "kms:ViaService": "sso.*.amazonaws.com"
        }
    }

    or this for Identity Store:

    "Condition": {
       "StringLike": {
          "kms:EncryptionContext:aws:identitystore:identitystore-arn": "${identity_store_arn}",
          "kms:ViaService": "identitystore.*.amazonaws.com"
        }
    }

Pricing and availability
Standard AWS KMS charges apply for key storage and API usage. Identity Center remains available at no additional cost.

This capability is now available in all AWS commercial Regions, AWS GovCloud (US), and AWS China Regions. To learn more, visit the IAM Identity Center User Guide.

We look forward to learning how you use this new capability to meet your security and compliance requirements.

— seb

Introducing Apache Airflow 3 on Amazon MWAA: New features and capabilities

Post Syndicated from Anurag Srivastava original https://aws.amazon.com/blogs/big-data/introducing-apache-airflow-3-on-amazon-mwaa-new-features-and-capabilities/

Today, Amazon Web Services (AWS) announced the general availability of Apache Airflow 3 on Amazon Managed Workflows for Apache Airflow (Amazon MWAA). This release transforms how organizations use Apache Airflow to orchestrate data pipelines and business processes in the cloud, bringing enhanced security, improved performance, and modern workflow orchestration capabilities to Amazon MWAA customers.

Amazon MWAA introduces Airflow 3 features that modernize workflow management for AWS customers. Following the April 2025 release of Airflow 3 by the Apache community, AWS has incorporated these capabilities into Amazon MWAA. Airflow now features a completely redesigned, intuitive UI that simplifies workflow orchestration for users across experience levels. With the Task Execution Interface (Task API), tasks can run both within Airflow and as standalone Python scripts, improving code portability and testing. Scheduler-managed Backfill moves operations from the CLI to the scheduler, providing centralized control and visibility through the Airflow UI. CLI security improvements replace direct database access with API calls, maintaining consistent security across interfaces. Airflow now supports event-driven workflows, enabling triggers from AWS services and external sources. Amazon MWAA also adds support for Python 3.12, bringing the latest language capabilities to workflow development.

This post explores the features of Airflow 3 on Amazon MWAA and outlines enhancements that improve your workflow orchestration capabilities. The service maintains the Amazon MWAA pay-as-you-go pricing model with no upfront commitments. You can begin immediately by visiting the Amazon MWAA console, launching new Apache Airflow environments through the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS CloudFormation, or AWS SDK within minutes.

Architectural advancements in Airflow 3 on Amazon MWAA

Airflow 3 on Amazon MWAA introduces significant architectural improvements that enhance security, performance, and flexibility. These advancements create a more robust foundation for workflow orchestration while maintaining backward compatibility with existing workflows.

Enhanced security

Amazon MWAA with Airflow 3 changes the security model by making component isolation a standard practice rather than optional. In Airflow 2, the DAG processor (the component that parses and processes DAG files) runs within the scheduler process by default, but can optionally be separated into its own process for better scalability and security isolation. Airflow 3 makes this separation standard, maintaining consistent security practices across deployments.

API server and Task API

Building on this security foundation, a new API server component is introduced in Amazon MWAA with Airflow 3, which serves as an intermediary between task instances and the Airflow metadata database. This change improves your workflows’ security posture by minimizing direct access to the Airflow metadata database from tasks. Tasks now operate with least privilege database access, reducing the risk of one task affecting others and improving overall system stability through fewer direct database connections.

The standardized communication through well-defined API endpoints creates a foundation for more secure, scalable, and flexible workflow orchestration. The Task Execution Interface (Task API) helps tasks run both within Airflow and as standalone Python scripts, improving code portability and testing capabilities.

From data-aware to event-driven scheduling

Airflow’s evolution toward event-driven scheduling began with the introduction of data-aware scheduling in Airflow 2.4, so DAGs could be triggered based on data availability rather than time schedules alone. Amazon MWAA with Airflow 3 builds on this foundation through a transition that includes the renaming of datasets to assets and introduces advanced capabilities, including asset partitions, external event integration, and asset-centric workflow design.

The transition from datasets to assets represents more than a simple rename. A data asset is a collection of logically related data that can represent diverse data products, including database tables, persisted ML models, embedded dashboards, or directories containing files.

Amazon MWAA with Airflow 3 introduces a new asset-centric syntax that represents an important shift in how workflows can be designed. The @asset decorator helps developers put data assets at the center of their workflow design, creating more intuitive asset-driven pipelines.

The following code is an example of asset-aware DAG scheduling:

from airflow.sdk import DAG, Asset
from airflow.providers.standard.operators.python import PythonOperator

# Define the asset
customer_data_asset = Asset(name="customer_data", uri="s3://my-bucket/customer-data.csv")

def process_customer_data():
    """Process customer data..."""
    # Implementation here

# Create the DAG and task
with DAG(dag_id="process_customer_data", schedule="@daily"):
    PythonOperator(
        task_id="process_data", 
        outlets=[customer_data_asset], 
        python_callable=process_customer_data
    )

The following code shows an asset-centric approach with the @asset decorator:

from airflow.sdk import asset

@asset(uri="s3://my-bucket/customer-data.csv", schedule="@daily")
def customer_data():
    """Process customer data..."""
    # Implementation here

The @asset decorator automatically creates an asset with the function name, a DAG with the same identifier, and a task that produces the asset. This reduces code complexity and facilitates automatic DAG creation, where each asset becomes a self-contained workflow unit.

External event-driven scheduling with Asset Watchers

A significant advancement in Amazon MWAA with Airflow 3 is the introduction of Asset Watchers, which help Airflow react to events happening outside of the Airflow system itself. Whereas previous versions supported internal cross-DAG dependencies, Asset Watchers extend this capability to external data systems and message queues through the AssetWatcher class.

Amazon MWAA with Airflow 3 includes support for Amazon Simple Queue Service (Amazon SQS) through Asset Watchers. This allows your workflows to be triggered by external messages and facilitates more event-driven scheduling. Airflow now supports event-driven workflows, enabling triggers from AWS services and external sources. Asset Watchers monitor external systems asynchronously and trigger workflow execution when specific events occur, enabling workflows to respond to business events, data updates, or system notifications without the overhead of traditional sensor-based polling mechanisms.

Modern React-based UI

Amazon MWAA with Airflow 3 features a completely redesigned, intuitive UI built with React and FastAPI that simplifies workflow orchestration for users across experience levels. The new interface provides more intuitive navigation and workflow visualization, with an enhanced grid view that offers better visibility into task status and history. Users will appreciate the addition of dark mode support, which reduces eye strain during extended use, and the overall faster performance that’s especially noticeable when working with large DAGs.

The new UI maintains familiar workflows while providing a more modern and efficient experience for DAG management and monitoring, making daily operations more productive for both developers and operators. The legacy UI has been completely removed, offering a cleaner, more consistent experience across the system. The foundation for the new UI is built on REST APIs and a set of internal APIs for UI operations, both of which are now based on FastAPI, creating a more cohesive and secure architecture for both programmatic access and UI operations.

Scheduler optimizations

Amazon MWAA with Airflow 3’s enhanced scheduler delivers performance improvements for task execution and workflow management. The redesigned scheduling engine processes tasks more efficiently, reducing the time between task submissions and executions. This optimization benefits data pipeline operations that require rapid task processing and timely workflow completion.

The scheduler now manages computing resources more effectively, enabling stable performance even as workloads scale. When running multiple DAGs simultaneously, the improved resource allocation system helps prevent bottlenecks and maintains consistent execution speeds. This advancement is particularly useful for organizations running complex workflows with varying resource requirements. The new scheduler also handles concurrent operations with increased precision, so teams can run multiple DAG instances simultaneously while maintaining system stability and predictable performance.

Enhanced scheduler backfill operations

Scheduler-managed backfill (the process of running DAGs for historical dates) moves operations from the CLI to the scheduler, providing centralized control and visibility through the Airflow UI. Amazon MWAA with Airflow 3 delivers important upgrades to the scheduler’s backfill capabilities, helping data teams process historical data more efficiently. The backfill process has been optimized for better performance, reducing the database load during these operations and making sure backfills can be completed more quickly, minimizing the impact on near real-time workflow execution.

Amazon MWAA with Airflow 3 also improves the management of backfill operations, with the scheduler providing better isolation between backfill jobs and supporting more efficient processing of historical datasets. Operators now have better monitoring tools to track the progress and status of their backfill jobs, resulting in more effective management of these critical data processing tasks.

Developer-focused improvements

Airflow 3 on Amazon MWAA delivers several enhancements designed to improve the developer experience, from simplified task definition to better workflow management capabilities.

Task SDK

The Task SDK provides a more intuitive way to define tasks and DAGs:

# Example using the Task SDK
from airflow.sdk import dag, task
from datetime import datetime

@dag(
    start_date=datetime(2023, 1, 1),
    schedule="@daily",
    catchup=False
)
def modern_etl_workflow():
    
    @task
    def extract():
        # Extract data from source
        return {"data": [1, 2, 3, 4, 5]}
    
    @task
    def transform(input_data):
        # Transform the data
        return [x * 10 for x in input_data]
    
    @task
    def load(transformed_data):
        # Load data to destination
        print(f"Loading data: {transformed_data}")
    
    # Define the workflow
    extracted_data = extract()
    transformed_data = transform(extracted_data["data"])
    load(transformed_data)

# Instantiate the DAG
etl_dag = modern_etl_workflow()

This approach offers more intuitive data flow between tasks, better integrated development environment (IDE) support with improved type hinting, and more straightforward unit testing of task logic. The result is cleaner, more maintainable code that better represents the actual data flow of your pipelines. Teams adopting this pattern often find their DAGs become more readable and simpler to maintain over time, especially as workflows grow in complexity.

DAG versioning

Amazon MWAA with Airflow 3 includes basic DAG versioning capabilities that come by default with Airflow 3. Each time a DAG is modified and deployed, Airflow serializes and stores the DAG definition to preserve history. This automatic version tracking minimizes the need for manual record-keeping and ensures every modification is documented.

Through the Airflow UI, teams can access and review the history of their DAGs. This visual representation shows version numbers (v1, v2, v3, etc.) and helps teams understand how their workflows have evolved over time.

The DAG versioning supported in Amazon MWAA provides the capability to see different DAG versions that were run in the Airflow UI, offering improved workflow visibility and enhanced collaboration for data engineering teams managing complex, evolving data pipelines.

Python 3.12 support

Amazon MWAA adds support for Python 3.12, bringing the latest language capabilities to workflow development. This upgrade provides access to the latest Python language improvements, performance enhancements, and library updates, keeping your data pipelines modern and efficient.

Features not currently supported in Amazon MWAA

Although we are launching most of the Airflow 3 features on Amazon MWAA in this release, some features are not supported at this time:

  • DAG versioning (AIP-63) – Advanced versioning features beyond basic version tracking
  • Replace Flask AppBuilder (AIP-79) – Full replacement capabilities
  • Edge Executor and task isolations (AIP-69) – Remote execution capabilities
  • Multi-language support (AIP-72) – Support for languages other than Python

We plan to support these features in subsequent versions of Airflow on Amazon MWAA.

Conclusion

Airflow 3 on Amazon MWAA delivers enhanced workflow automation capabilities. The architectural improvements, enhanced security model, and developer-friendly features provide a solid foundation for building more reliable and maintainable data pipelines.The introduction of Asset Watchers changes how workflows can respond to external events, enabling truly event-driven scheduling. This capability, combined with the new asset-centric workflow design, makes Airflow 3 a more powerful and flexible orchestration service.

The scheduler optimizations deliver performance improvements for task execution and workflow management, and the enhanced backfill capabilities make historical data processing more efficient. The DAG versioning system improves workflow stability and collaboration, and Python 3.12 support keeps your data pipelines modern and efficient.

Organizations can now take advantage of these new features and improvements in Airflow 3 on Amazon MWAA to enhance their workflow orchestration capabilities. To get started, visit the Amazon MWAA product page.


About the authors

Anurag Srivastava works as a Senior Big Data Cloud Engineer at Amazon Web Services (AWS), specializing in Amazon MWAA. He’s passionate about helping customers build scalable data pipelines and workflow automation solutions on AWS.
Kamen Sharlandjiev is a Sr. Big Data and ETL Solutions Architect, Amazon MWAA and AWS Glue ETL expert. He’s on a mission to make life easier for customers who are facing complex data integration and orchestration challenges. His secret weapon? Fully managed AWS services that can get the job done with minimal effort. Follow Kamen on LinkedIn to keep up to date with the latest Amazon MWAA and AWS Glue features and news!
Ankit Sahu brings over 18 years of expertise in building innovative digital products and services. His diverse experience spans product strategy, go-to-market execution, and digital transformation initiatives. Currently, Ankit serves as Senior Product Manager at Amazon Web Services (AWS), where he leads the Amazon MWAA service.
Mohammad Sabeel works as a Senior Cloud Support Engineer at Amazon Web Services (AWS), specializing in AWS Analytics services including AWS Glue, Amazon MWAA, and Amazon Athena. With over 14 years of IT experience, he’s passionate about helping customers build scalable data processing pipelines and optimize their analytics solutions on AWS.
Satya Chikkala is a Solutions Architect at Amazon Web Services. Based in Melbourne, Australia, he works closely with enterprise customers to accelerate their cloud journey. Beyond work, he is very passionate about nature and photography.
Sriharsh Adari is a Senior Solutions Architect at Amazon Web Services (AWS), where he helps customers work backward from business outcomes to develop innovative solutions on AWS. Over the years, he has helped multiple customers on data system transformations across industry verticals. His core area of expertise include technology strategy, data analytics, and data science. In his spare time, he enjoys playing sports, binge-watching TV shows, and playing Tabla.
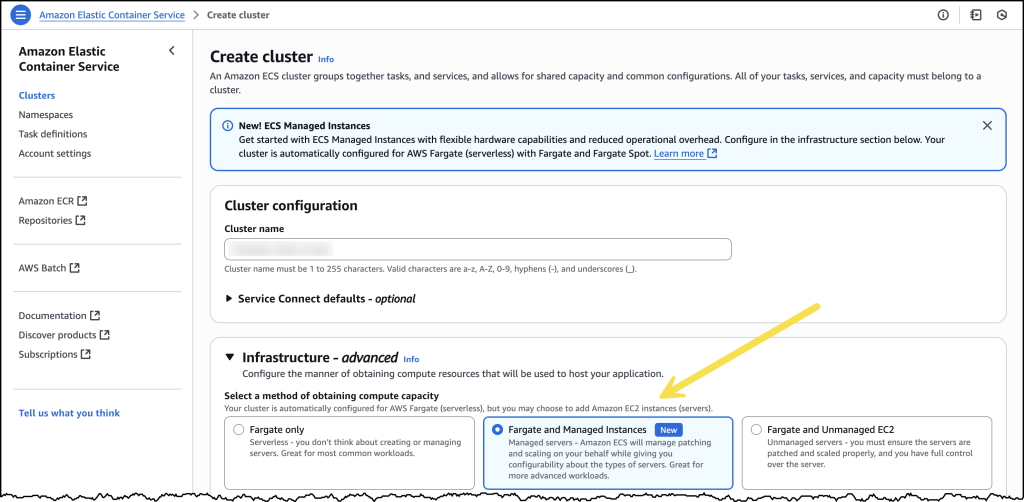
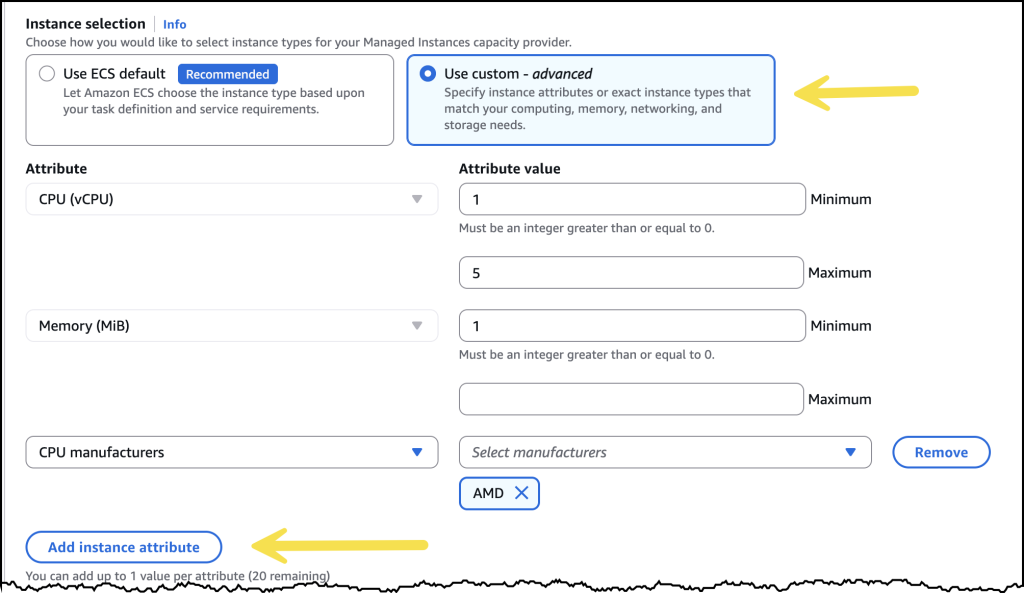
Announcing Amazon ECS Managed Instances for containerized applications

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/announcing-amazon-ecs-managed-instances-for-containerized-applications/

Today, we’re announcing Amazon ECS Managed Instances, a new compute option for Amazon Elastic Container Service (Amazon ECS) that enables developers to use the full range of Amazon Elastic Compute Cloud (Amazon EC2) capabilities while offloading infrastructure management responsibilities to Amazon Web Service (AWS). This new offering combines the operational simplicity of offloading infrastructure with the flexibility and control of Amazon EC2, which means customers can focus on building applications that drive innovation, while reducing total cost of ownership (TCO) and maintaining AWS best practices.

Customers running containerized workloads told us they want to combine the simplicity of serverless with the flexibility of self-managed EC2 instances. Although serverless options provide an excellent general-purpose solution, some applications require specific compute capabilities, such as GPU acceleration, particular CPU architectures, or enhanced networking performance. Additionally, customers with existing Amazon EC2 capacity investments through EC2 pricing options couldn’t fully use these commitments with serverless offerings.

Amazon ECS Managed Instances provides a fully managed container compute environment that supports a broad range of EC2 instance types and deep integration with AWS services. By default, it automatically selects the most cost-optimized EC2 instances for your workloads, but you can specify particular instance attributes or types when needed. AWS handles all aspects of infrastructure management, including provisioning, scaling, security patching, and cost optimization, enabling you to concentrate on building and running your applications.

Let’s try it out

Looking at the AWS Management Console experience for creating a new Amazon ECS cluster, I can see the new option for using ECS Managed Instances. Let’s take a quick tour of all the new options.

Creating a ECS cluster with Managed Instances

After I’ve selected Fargate and Managed Instances, I’m presented with two options. If I select Use ECS default, Amazon ECS will choose general purpose instance types based on grouping together pending Tasks, and picking the optimum instance type based on cost and resilience metrics. This is the most straightforward and recommended way to get started. Selecting Use custom – advanced opens up additional configuration parameters, where I can fine-tune the attributes of instances Amazon ECS will use.

Creating a ECS cluster with Managed Instances

By default, I see CPU and Memory as attributes, but I can select from 20 additional attributes to continue to filter the list of available instance types Amazon ECS can access.

Creating a ECS cluster with Managed Instances

After I’ve made my attribute selections, I see a list of all the instance types that match my choices.

Creating a ECS cluster with Managed Instances

From here, I can create my ECS cluster as usual and Amazon ECS will provision instances for me on my behalf based on the attributes and criteria I’ve defined in the previous steps.

Key features of Amazon ECS Managed Instances

With Amazon ECS Managed Instances, AWS takes full responsibility for infrastructure management, handling all aspects of instance provisioning, scaling, and maintenance. This includes implementing regular security patches initiated every 14 days (due to instance connection draining, the actual lifetime of the instance may be longer), with the ability to schedule maintenance windows using Amazon EC2 event windows to minimize disruption to your applications.

The service provides exceptional flexibility in instance type selection. Although it automatically selects cost-optimized instance types by default, you maintain the power to specify desired instance attributes when your workloads require specific capabilities. This includes options for GPU acceleration, CPU architecture, and network performance requirements, giving you precise control over your compute environment.

To help optimize costs, Amazon ECS Managed Instances intelligently manages resource utilization by automatically placing multiple tasks on larger instances when appropriate. The service continually monitors and optimizes task placement, consolidating workloads onto fewer instances to dry up, utilize and terminate idle (empty) instances, providing both high availability and cost efficiency for your containerized applications.

Integration with existing AWS services is seamless, particularly with Amazon EC2 features such as EC2 pricing options. This deep integration means that you can maximize existing capacity investments while maintaining the operational simplicity of a fully managed service.

Security remains a top priority with Amazon ECS Managed Instances. The service runs on Bottlerocket, a purpose-built container operating system, and maintains your security posture through automated security patches and updates. You can see all the updates and patches applied to the Bottlerocket OS image on the Bottlerocket website. This comprehensive approach to security keeps your containerized applications running in a secure, maintained environment.

Available now

Amazon ECS Managed Instances is available today in US East (North Virginia), US West (Oregon), Europe (Dublin), Africa (Cape Town), Asia Pacific (Singapore), and Asia Pacific (Tokyo) AWS Regions. You can start using Managed Instances through the AWS Management Console, AWS Command Line Interface (AWS CLI), or infrastructure as code (IaC) tools such as AWS Cloud Development Kit (AWS CDK) and AWS CloudFormation. You pay for the EC2 instances you use plus a management fee for the service.

To learn more about Amazon ECS Managed Instances, visit the documentation and get started simplifying your container infrastructure today.

Introducing Claude Sonnet 4.5 in Amazon Bedrock: Anthropic’s most intelligent model, best for coding and complex agents

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/introducing-claude-sonnet-4-5-in-amazon-bedrock-anthropics-most-intelligent-model-best-for-coding-and-complex-agents/

Today, we’re excited to announce that Claude Sonnet 4.5, powered by Anthropic, is now available in Amazon Bedrock, a fully managed service that offers a choice of high- performing foundation models from leading AI companies. This new model builds upon Claude 4’s foundation to achieve state-of-the-art performance in coding and complex agentic applications.

Claude Sonnet 4.5 demonstrates advancements in agent capabilities, with enhanced performance in tool handling, memory management, and context processing. The model shows marked improvements in code generation and analysis, from identifying optimal improvements to exercising stronger judgment in refactoring decisions. It particularly excels at autonomous long-horizon coding tasks, where it can effectively plan and execute complex software projects spanning hours or days while maintaining consistent performance and reliability throughout the development cycle.

By using Claude Sonnet 4.5 in Amazon Bedrock, developers gain access to a fully managed service that not only provides a unified API for foundation models but ensures their data stays under complete control with enterprise-grade tools for security, and optimization.

Claude Sonnet 4.5 also seamlessly integrates with Amazon Bedrock AgentCore, enabling developers to maximize the model’s capabilities for building complex agents. AgentCore’s purpose-built infrastructure complements the model’s enhanced abilities in tool handling, memory management, and context understanding. Developers can leverage complete session isolation, 8-hour long-running support, and comprehensive observability features to deploy and monitor production-ready agents from autonomous security operations to complex enterprise workflows.

Business applications and use cases
Beyond its technical capabilities, Sonnet 4.5 delivers practical business value through consistent performance and advanced problem-solving abilities. The model excels at producing and editing business documents while maintaining reliable performance across complex workflows.

The model demonstrates strength in several key industries:

  • Cybersecurity – Claude Sonnet 4.5 can be used to deploy agents that autonomously patch vulnerabilities before exploitation, shifting from reactive detection to proactive defense.
  • Finance – Sonnet 4.5 handles everything from entry-level financial analysis to advanced predictive analysis, helping transform manual audit preparation into intelligent risk management.
  • Research – Sonnet 4.5 can better handle tools, context, and deliver ready-to-go office files to drive expert analysis into final deliverables and actionable insights.

Sonnet 4.5 features in the Amazon Bedrock API
Here are some highlights of Sonnet 4.5 in the Amazon Bedrock API:

Smart Context Window Management – The new API introduces intelligent handling when AI models reach their maximum capacity. Instead of returning errors when conversations get too long, Claude Sonnet 4.5 will now generate responses up to the available limit and clearly indicate why it stopped. This eliminates frustrating interruptions and allows users to maximize their available context window.

Tool Use Clearing for Efficiency – Claude Sonnet 4.5 enables automatic cleanup of tool interaction history during long conversations. When conversations involve multiple tool calls, the system can automatically remove older tool results while preserving recent ones. This keeps conversations efficient and prevents unnecessary token consumption, reducing costs while maintaining conversation quality.

Cross-Conversation Memory – A new memory capability enables Sonnet 4.5 to remember information across different conversations through the use of a local memory file. Users can explicitly ask the model to remember preferences, context, or important information that persists beyond a single chat session. This creates more personalized and contextually aware interactions while keeping the information safe within the local file.

With these new capabilities for managing context, developers can build AI agents capable of handling long-running tasks at higher intelligence without hitting context limits or losing critical information as frequently.

Getting started
To begin working with Claude Sonnet 4.5, you can access it through Amazon Bedrock using the correct model ID. A good practice is to use the Amazon Bedrock Converse API to write code once and seamlessly switch between different models, making it easier to experiment with Sonnet 4.5 or any of the other models available in Amazon Bedrock.

Let’s see this in action with a simple example. I’m going to use the Amazon Bedrock Converse API to send a prompt to Sonnet 4.5. I start by importing the modules I’m going to use. For this short example, I only need AWS SDK for Python (Boto3) so I can create a BedrockRuntimeClient. I’m also importing the rich package so I can format my output nicely later on.

Following best practices, I create a boto3 session and create an Amazon Bedrock client from it instead of creating one directly. This gives you explicit control over configuration, improves thread safety, and makes your code more predictable and testable compared to relying on the default session.

I want to give the model something with a bit of complexity instead of asking a simple question to demonstrate the power of Sonnet 4.5. So I’m going to give the model the current state of an imaginary legacy monolithic application written in Java with a single database and ask for a digital transformation plan which includes a migration strategy, risk assessment, estimated timeline and key milestones and specific AWS services recommendations.

Because the prompt is quite long I put it in a text file locally and just load it up in code. I then set up the Amazon Bedrock converse payload setting the role to “user” to indicate that this is a message by the user of the application and add the prompt to the content.

This is where the magic happens! We put it all together and call Claude Sonnet 4.5 using its model ID. Well, kind of. You can only access Sonnet 4.5 through an inference profile. This defines which AWS Regions will process your model requests and helps manage throughput and performance.

For this demo, I’ll be using one of Amazon Bedrock’s system-defined cross-Region inference profiles, which automatically routes requests across multiple Regions for optimal performance.

Now I just need to print to the screen to see the results. This is where I use the rich package I imported earlier just so we may have a nicely formatted output as I’m expecting a long response for this one. I also save the output to a file so I can have it handy as something to share with my teams.

Ok, let’s check the results! As expected, Sonnet 4.5 worked through my requirements and provided extensive and deep guidance for my digital transformation plan that I could start putting into practice. It included an executive summary, a step-by-step migration strategy split into phases with time estimates, and even some code samples to seed the development process and start breaking things down into microservices. It also provided the business cases for introducing technology and recommended the correct AWS services for each scenario. Here are some highlights from the report.

Claude Sonnet 4.5 is able to maintain consistency while delivering creative solutions making it an ideal choice for businesses seeking to use AI for complex problem-solving and development tasks. Its enhanced capabilities in following directions and using tools effectively translate into more reliable and innovative solutions across various business contexts.

Things to know
Claude Sonnet 4.5 represents a significant step forward in agent capabilities, particularly excelling in areas where consistent performance and creative problem-solving are essential. Its enhanced abilities in tool handling, memory management, and context processing make it particularly valuable across key industries such as finance, research, and cybersecurity. Whether handling complex development lifecycles, executing long-running tasks, or tackling business-critical workflows, Claude Sonnet 4.5 combines technical excellence with practical business value.

Claude Sonnet 4.5 is available today. For detailed information about its availability please visit the documentation.

To learn more about Amazon Bedrock explore our self-paced Amazon Bedrock Workshop and discover how to use available models and their capabilities in your applications.

AWS Weekly Roundup: Amazon S3, Amazon Bedrock AgentCore, AWS X-Ray and more (September 29, 2025)

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-s3-amazon-bedrock-agentcore-aws-x-ray-and-more-september-29-2025/

Wow, can you all believe it? We’re nearing the end of the year already. Next thing you know, AWS re:Invent will be here! This is our biggest event that takes place every year in Las Vegas from December 1st to December 5th where we reveal and release many of the things that we’ve been working on. If you haven’t already, buy your tickets to AWS re:Invent 2025 to experience it in person. If you can’t make it to Vegas, don’t worry, make sure to stay tuned here on the AWS News Blog where will be covering many of the announcements as they happen.

However, there are plenty of new exciting new releases between now and then, so, as usual, let’s take a quick look at some of the highlights from last week so you can catch up on what’s been recently launched, starting with one of the most popular services: Amazon S3!

S3 updates
The S3 team has been working really hard to make working with S3 even better. This month alone has seen releases such as bulk target selection for S3 Batch Operations, support for conditional deletes in S3 general purpose buckets, increased file size and archive scanning limits for malware protection, and more.

Last week was another S3 milestone with the addition of a preview in the AWS Console for Amazon S3 Tables. You can now take a quick peek at your S3 Tables right from the console, making it easier to understand their data structure and content without writing any SQL. This viewer-friendly feature is ready to use across all regions where S3 Tables are supported, with costs limited to just the S3 requests needed to display your table preview.

Other releases
Here are some highlights from other services which also released some great stuff this week.

Amazon Bedrock AgentCore expands enterprise integration and automation options — Bedrock AgentCore services are leveling up their enterprise readiness with new support for Amazon VPC connectivity, AWS PrivateLink, AWS CloudFormation, and resource tagging, giving developers more control over security and infrastructure automation. These enhancements let you deploy AI agents that can securely access private resources, automate infrastructure deployment, and maintain organized resource management whether you’re using AgentCore Runtime for scalable agent deployment, Browser for web interactions, or Code Interpreter for secure code execution.

AWS X-Ray brings smart sampling for better error detection — AWS X-Ray now offers adaptive sampling that automatically adjusts trace capture rates within your defined limits, helping DevOps teams and SREs catch critical issues without oversampling during normal operations. The new capability includes Sampling Boost for increased sampling during anomalies and Anomaly Span Capture for targeted error tracing, giving teams better observability exactly when they need it while keeping costs in check.

AWS Clean Rooms enhances real-time collaboration wilth incremental ID mapping — AWS Clean Rooms now lets you update ID mapping tables with only new, modified, or deleted records through AWS Entity Resolution, making data synchronization across collaborators more efficient and timely. This improvement helps measurement providers maintain fresh datasets with advertisers and publishers while preserving privacy controls, enabling always-on campaign measurement without the need to reprocess entire datasets.

Short and sweet
Here are some bite-sized updates that could prove really handy for your teams or workloads.

Keeping up with the latest EC2 instance types can be challenging. AWS Compute Optimizer now supports 99 additional instance types including the latest C8, M8, R8, and I8 families.

In competitive gaming, every millisecond counts! Amazon GameLift has launched a new Local Zone in Dallas bringing ultra-low latency game servers closer to players in Texas.

When managing large-scale Amazon EC2 deployments, control is everything! Amazon EC2 Allowed AMIs setting now supports filtering by marketplace codes, deprecation time, creation date, and naming patterns to help prevent the use of non-compliant images. Additionally, EC2 Auto Scaling now lets you force cancel instance refreshes immediately, giving you faster control during critical deployments.

Making customer service more intelligent and secure across languages! Amazon Connect introduces enhanced analytics in its flow designer for better customer journey insights, adds custom attributes for precise interaction tracking, and expands Contact Lens sensitive data redaction to support seven additional European and American languages.

That’s it for this week!

Don’t forget to check out all the upcoming AWS events happening across the globe. There are many exciting opportunities for you to attend free events where you can meet lots of people and learn a lot while enjoying a great day amongst other like-minded people in the tech industry.

And if you feel like competing for some cash, time is running out to be part of something extraordinary! The AWS AI Agent Global Hackathon continues until October 20, offering developers a unique opportunity to build innovative AI agents using AWS’s comprehensive gen AI stack. With over $45,000 in prizes and exclusive go-to-market opportunities up for grabs, don’t miss the chance to showcase your creativity and technical prowess in this global competition.

I hope you have found something useful or exciting within this last week’s launches. We post a weekly review every Monday to help you keep up with the latest from AWS so make sure to bookmark this and hopefully see you for the next one!

Matheus Guimaraes | @codingmatheus

Accelerate AI agent development with the Nova Act IDE extension

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/accelerate-ai-agent-development-with-the-nova-act-ide-extension/

Today, I’m excited to announce the Nova Act extension — a tool that streamlines the path to build browser automation agents without leaving your IDE. The Nova Act extension integrates directly into IDEs like Visual Studio Code (VS Code), Kiro, and Cursor, helping you to create web-based automation agents using natural language with the Nova Act model.

Here’s a quick look at the Nova Act extension in Visual Studio Code:

The Nova Act extension is built on top of the Amazon Nova Act SDK (preview), our browser automation agents SDK (Software Development Kit). The Nova Act extension transforms traditional workflow development by eliminating context switching between coding and testing environments. You can now build, customize, and test production-grade agent scripts—all within your IDE—using features like natural language based generation, atomic cell-style editing, and integrated browser testing. This unified experience accelerates development velocity for tasks like form filling, QA automation, search, and complex multi-step workflows.

You can start with the Nova Act extension by describing your workflow in natural language to quickly generate an initial agent script. Customize it using the notebook-style builder mode to integrate APIs, data sources, and authentication, then validate it with local testing tools that simulate real-world conditions, including live step-by-step debugging of lengthy multi-step workflows.

Getting started with the Nova Act extension
First, I need to install the Nova Act extension from the extension manager in my IDE. 

I’m using Visual Studio Code, and after choosing Extensions, I enter Nova Act. Then, I select the extension and choose Install. 

To get started, I need to obtain an API key. To do this, I navigate to the Nova Act page and follow the instructions to get the API key. I select Set API Key by opening the Command Palette with Cmd+Shift+P / Ctrl+Shift+P.

After I’ve entered my API key, I can try Builder Mode. This is a notebook-style builder mode that breaks complex automation scripts into modular cells, allowing me to test and debug each step individually before moving to the next.

Here, I can use the Nova Act SDK to build my agent. On the right side, I have a Live view panel to preview my agent’s actions in the browser and an Output panel to monitor execution logs, including the model’s thinking and actions.

To test the Nova Act extension, I choose Run all cells. This will start a new browser instance and act based on the given prompt.

I choose Fullscreen to see how browser automation works.

Another useful feature in Builder Mode is that I can navigate to the Output panel and select the cell to see its logs. This helps me debug or review logs specific to the cell I’m working on.

I can also select a template to get started.

Besides using Builder Mode, I can also chat with Nova Act to create a script for me. To do that, I select the extension and choose Generate Nova Act Script. The Nova Act extension opens a chat dialog in the right panel and automatically creates a script for me.

After I finish creating the script, I can choose Start Builder Mode, and the Nova Act extension will help me create a Python file in Builder Mode. This creates a seamless integration because I can switch between chat capability and Builder Mode.

In the chat interface, I see three workflow modes available:

  • Ask: Describe tasks in natural language to generate automation scripts
  • Edit: Refine or customize generated scripts before execution
  • Agent: Run, monitor, and interact with the AI agent performing the workflow

I can also add Context to provide relevant information about my active documents, instructions, problems, or additional Model Context Protocol (MCP) resources the agent can use, plus a screenshot of the current window. Providing this information helps the agent understand any specific requirements for the automation task.

The Nova Act extension also provides a set of predefined templates that I can access by entering / in the chat. These templates are predefined automation scenarios designed to help quickly generate scripts for common web tasks.

I can use these templates (for example, @novaAct /shopping [my requirements]) to get tailored Python scripts for my workflow. At launch, Nova Act extension provides the following templates:

  • /shopping: Automates online shopping tasks (searching, comparing, purchasing)
  • /extract: Handles data extraction
  • /search: Performs search and information gathering
  • /qa: Automates quality assurance and testing workflows
  • /formfilling: Completes forms and data entry tasks

This extension transforms my agent development workflow by positioning Nova Act extension as a full-stack agent builder tool—a complete agent IDE for the entire development lifecycle. I can prototype with natural language, customize with modular scripting, and validate with local testing—all without leaving my IDE—ensuring production-grade scripts.

Things to know
Here are key points to note:

  • Supported IDEs: At launch, the Nova Act extension is available for Visual Studio Code, Cursor, and Kiro, with additional IDE support planned
  • Open source: The Nova Act extension is available under the Apache 2.0 license, allowing for community contributions and customization
  • Pricing: The Nova Act extension is available at no charge.

Get started with Nova Act extension by installing it from your IDE’s extension marketplace or visiting the GitHub repository for documentation and examples.

Happy automating!
— Donnie

AWS named as a Leader in the 2025 Gartner Magic Quadrant for AI Code Assistants

Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/aws-named-as-a-leader-in-the-2025-gartner-magic-quadrant-for-ai-code-assistants/

We are excited to share that AWS has been named a Leader in the 2025 Gartner Magic Quadrant for AI Code Assistants for the second year in row. This recognition highlights for us Amazon Q Developer’s commitment to innovation and delivering exceptional customer experiences. We believe this Leader placement showcases our rapid pace of innovation, which makes the whole software development lifecycle easier and increases developer productivity with enterprise-grade access controls and security. We are honored to be recognized by Gartner and are committed to continuing to innovate on behalf of our customers.

A Gartner Magic Quadrant chart titled 'Magic Quadrant for AI Code Assistants' showing the positioning of various companies across four quadrants: Leaders, Challengers, Visionaries, and Niche Players. Companies like GitHub, Amazon, and Google Cloud are prominently positioned in the Leaders quadrant, while others like JetBrains appear in the Visionaries section. The chart plots vendors based on their 'Ability to Execute' (y-axis) and 'Completeness of Vision' (x-axis). Dated August 2025.

The Gartner Magic Quadrant evaluated AI code assistant providers based on their Ability to Execute and Completeness of Vision. Our innovations throughout the software life cycle (SDLC) include code generation, troubleshooting, transformation, cost optimization, and vulnerability scanning.

Leaders in this Magic Quadrant for AI Code Assistants continue to set the benchmark for end-to-end developer enablement through advanced AI capabilities. They consistently integrate cutting-edge models into robust, agentic workflows that enhance productivity, code quality, and security across the SDLC. These vendors exhibit a sharp understanding of enterprise needs, translating customer feedback into iterative improvements and differentiated innovation — such as long-context reasoning, hybrid deployment flexibility, and seamless integration across IDEs and DevSecOps platforms. Leaders also stand out through their operational maturity, supporting global enterprises with scalable infrastructure, regulatory compliance, and strong service-level reliability. Their growing ecosystems, deepening product integration, and strategic clarity ensure sustained influence across diverse developer and enterprise environments.

Access the complete 2025 Gartner Magic Quadrant for AI Code Assistants report to learn more and get started with Amazon Q Developer today.

Unlock new possibilities: AWS Organizations service control policy now supports full IAM language

Post Syndicated from Swara Gandhi original https://aws.amazon.com/blogs/security/unlock-new-possibilities-aws-organizations-service-control-policy-now-supports-full-iam-language/

Amazon Web Service (AWS) recently announced that AWS Organizations now offers full AWS Identity and Access Management (IAM) policy language support for service control policies (SCPs). With this feature, you can use conditions, individual resource Amazon Resource Names (ARNs), and the NotAction element with Allow statements. Additionally, you can now use wildcards at the beginning or middle of the Action element strings and implement the NotResource element in both Allow and Deny statements in SCPs. This feature is now available across AWS commercial and AWS GovCloud (US) Regions.

In this blog post, we walk through a set of newly supported SCP language capabilities that simplify permission management cases. These enhancements enable more intuitive and concise policy designs. We explore how these capabilities address past limitations to reduce operational overhead and improve policy readability. We also show what the previous implementation looked like and provide an example of how the new capability makes the intent clearer and implementation simpler.

Overview of the newly supported elements

The following table lists the supported SCP language elements along with their purpose and applicable effects. Elements and effects shown in bold indicate newly supported capabilities.

Element Purpose Supported effects
Version Specifies the language syntax rules to use for processing the policy. Allow, Deny
Statement Serves as the container for policy elements. You can have multiple statements in an SCP. Allow, Deny
Statement ID (Sid) (Optional) Provides a friendly name for the statement. Allow, Deny
Effect Defines whether the SCP statement allows or denies access to the IAM users and roles in an account. Allow, Deny
Action Specifies the AWS service and actions that the SCP allows or denies. Allow, Deny
NotAction Specifies the AWS service and actions that are exempt from the SCP. Used instead of the Action element. Allow, Deny
Resource Specifies the AWS resources that the SCP applies to. Allow, Deny
NotResource Specifies the AWS resources that are exempt from the SCP. Used instead of the Resource element. Allow, Deny
Condition Specifies the conditions for when the statement is in effect. Allow, Deny

Additionally, you can now use the wildcard characters * and ? anywhere in the Action or NotAction element. Previously, these wildcards were only allowed by themselves or at the end of an element. For example, all of the following are now valid:

  • "servicename:action*"
  • "servicename:*action"
  • "servicename:some*action"
  • "servicename:*"

Navigating new SCP language capabilities

Let’s explore recommended policy strategies and best practices by walking through some examples.

Using Deny with NotResource

You can use the NotResource element to apply a policy across resources except those explicitly listed. This is especially useful for implementing broad deny-by-default policies with scoped exceptions, simplifying policy structure while enforcing strong boundaries.

Example 1:

The goal of this example is to enforce a resource perimeter that blocks access to resources outside the organization, except for a defined set of service-owned resources.

  • Previous implementation: The policy used a tag-based approach to manage exceptions. It required tagging IAM principals with dp:exclude:resource:s3=true to grant access to external resources. This created operational overhead in tag management and introduced potential security risks if tags were incorrectly applied.
  • Improved implementation: With support for NotResource in Deny statements, the updated SCP uses a single, consolidated Deny statement denying the action except for a defined set of AWS-owned resources.
Policy structure before NotResource support Policy structure after NotResource support
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceResourcePerimeterAWSResourcesS3",
      "Effect": "Deny",
      "Action": "s3:GetObject",
      "Resource": "*",
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:ResourceOrgID": "<my-org-id>",
          "aws:PrincipalTag/dp:exclude:resource:s3": "true"
        }
      }
    }
  ]
}

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceResourcePerimeterAWSResources",
      "Effect": "Deny",
      "Action": "s3:GetObject",
      "NotResource": [
        "arn:aws:s3:::service-owned-bucket/*",
        "arn:aws:s3:::service-owned-bucket2/*"
      ],
      "Condition": {
        "StringNotEquals": {
          "aws:ResourceOrgID": "<org-id>"
        }      
       }
    }
  ]
}

Example 2:

This example denies access to Amazon Bedrock models except for one specific model.

  • Before this change: SCP relied on a broad permission baseline for AWS accounts within the organization by allowing access to Amazon Bedrock actions by default, while explicitly denying invocation of three specific models (examples: Deepseek, Anthropic, and meta). However, this approach requires continuous operational overhead to make sure policies are updated to deny access to newly added models to avoid exposure to potentially unwanted models.
  • Improved implementation: With support for NotResource in Deny statements, the updated SCP uses a single, consolidated Deny statement that denies actions except Amazon models.
Policy structure before NotResource support Policy structure after NotResource support
{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Effect": "Allow",
			"Action": "bedrock:*",
			"Resource": "*"
		},
		{
			"Effect": "Deny",
			"Action": [
				"bedrock:InvokeModel",
				"bedrock:InvokeModelWithResponseStream",
				"bedrock:PutFoundationModelEntitlement"
			],
			"Resource": [
				"arn:aws:bedrock:*::foundation-model/deepseek.*",
				"arn:aws:bedrock:*::foundation-model/anthropic.*",
				"arn:aws:bedrock:*::foundation-model/meta.*"
			]
		}
	]
}

{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Effect": "Allow",
			"Action": "bedrock:*",
			"Resource": "*"
		},
		{
			"Sid": "Statement1",
			"Effect": "Deny",
			"Action": [
				"bedrock:InvokeModel",
				"bedrock:InvokeModelWithResponseStream",
				"bedrock:PutFoundationModelEntitlement"
			],
			"NotResource": [
				"arn:aws:bedrock:*::foundation-model/amazon.*"
			]
		}
	]
}

Using Allow with conditions

By using the Condition element, you can specify the circumstances under which a policy statement is in effect. While optional, this element is now supported in Allow statements within SCPs, enabling more precise and scalable access control.

Note: We recommend using explicit Deny statements when authoring SCPs in most cases. Using Deny statements help make sure that each control works independently and remains enforceable. Relying solely on allow statements and the implicit deny-by-default model can lead to unintended access, because broader or overlapping Allow statements can override more restrictive ones.

The following example allows access to specific AWS services in certain AWS Regions.

  • Before this change: The policy uses a single Allow statement under the Sid: AllowSpecificServices. It lists broad service-level actions (for example, "ec2:", "s3:", and so on) in the Action element and applies them across resources ("Resource": "*"). Because AWS SCPs operate under a deny-by-default model, this setup effectively permits actions across the listed services while implicitly denying access to other services not included. For example, an explicit Deny restricts actions outside us-east-1, us-west-2, and eu-central-1 using a Region condition.
  • Improved implementation: In the updated example, the policy allows the same services, but only when they are requested in specific Regions (for example, "us-east-1", "us-west-2", and "eu-central-1"). This is achieved using the aws:RequestedRegion condition key in the Allow statement. This enhancement allows organizations to retain basic Allow logic while introducing contextual boundaries—such as limiting access by Region, account, or resource tag—previously only possible with Deny conditions.

Note: We recommend using one broad Allow statement and multiple targeted Deny statements in your policies. Avoid writing additional Allow statements that might overlap, because doing so could lead to unintended access. The recommended approach is to start with a broad Allow statement and then use Deny statements to refine and restrict access as needed.

Policy structure before support for Allow with conditions Policy structure after support for Allow with conditions
{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Sid":"AllowSpecificServices",
         "Effect":"Allow",
         "Action":[
            "ec2:*",
            "s3:*",
            "rds:*",
            "lambda:*",
            "cloudformation:*",
            "iam:*",
            "cloudwatch:*"
         ],
         "Resource":"*"
      },
      {
         "Sid":"AllowAccessOnlyTo3Regions",
         "Effect":"Deny",
         "Action":"*",
         "Resource":"*",
         "Condition":{
            "StringNotEquals":{
               "aws:RequestedRegion":[
                  "us-east-1",
                  "us-west-2",
                  "eu-central-1"
               ]
            }
         }
      }
   ]
}

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowServicesBasedOnRegion",
      "Effect": "Allow",
      "Action": [
        "ec2:*",
        "s3:*",
        "rds:*",
        "lambda:*",
        "cloudformation:*",
        "iam:*",
        "cloudwatch:*"
      ],
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "aws:RequestedRegion": [
            "us-east-1",
            "us-west-2",
            "eu-central-1"
          ]
        }
      }
    }
  ]
}

Other newly supported elements

To bring SCPs to full IAM policy language support, additional elements are now supported. While technically valid, some of these constructs require additional considerations and testing in practice because of their potential for unintended access if not carefully managed.

Newly supported feature Important considerations
Action with wildcards (*, ?) Can help shorten policies but use with caution—new actions added by AWS will match existing wildcard patterns as designed, potentially granting unintended permissions.
NotAction with wildcards (*, ?) We recommend using NotAction with a Deny statement if you want to deny all actions except those listed, which helps future-proof your controls (for example, denying everything in Amazon EC2 except actions that don’t match “*vpn*”.
Allow with NotResource Limited use cases. While supported, Allow with NotResource can default to including all resources—potentially allowing access to new resources added later. Use with caution and prefer explicit Deny statements when possible.
Allow with NotAction Limited use cases. While supported, Allow with NotAction can unintentionally permit access to new actions added by AWS. Use with caution and prefer explicit Deny statements to maintain control as services evolve.
Allow with Resource other than wildcard “*”. When using Allow with specific resources (not "*"), make sure your policy design avoids conflicting or overlapping Allow statements. Start with a broad Allow, then use targeted Deny statements to restrict access—this helps prevent unintended access from overlapping Allow statements.

Validate your policies with IAM Access Analyzer

You can use AWS IAM Access Analyzer to validate your SCPs before applying them, using both policy validation and custom policy checks.

IAM Access Analyzer validates your policy against IAM policy grammar and best practices. You can view policy validation check findings that include security warnings, errors, general warnings, and suggestions. These findings provide actionable recommendations to help you author policies that are both functional and aligned with security best practices.

Custom policy checks are an IAM Access Analyzer capability that security teams can use to help them accurately and proactively identify critical permissions in their policies. Custom policy checks can determine whether a new version of a policy is more permissive than the previous version. They use automated reasoning—a form of static analysis—to provide a higher level of security assurance in the cloud.

Custom policy checks can be embedded into continuous integration and continuous delivery (CI/CD) pipelines, so that policies can be checked without being deployed. Developers can also run custom policy checks from their local development environments and receive fast feedback on whether the policies they are authoring comply with your organization’s security standards. For more information refer to introducing IAM Access Analyzer custom policy checks.

Conclusion

The latest enhancements to AWS service control policies improve policy expressiveness and precision while reducing operational effort. By enabling constructs like Allow with conditions and specific resource ARNs, supporting NotResource in Deny statements, and expanding wildcard flexibility, you can simplify your policies and avoid layered or complex policies to achieve your goals. These updates bring SCPs in parity with IAM policy capabilities and empower organizations to implement cleaner, more intuitive access controls. As a best practice, it’s important to use these capabilities carefully—especially wildcard use—to avoid unintended permissions as AWS services evolve. We also encourage the implementation of explicit Deny statements as a best practice and using Allow statements when needed.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Swara Gandhi

Swara Gandhi

Swara is a Senior Solutions Architect on the AWS Identity Solutions team. She works on building secure and scalable end-to-end identity solutions. She is passionate about everything identity, security, and cloud.

Niti Prasad

Niti Prasad

Niti is a Senior Security Solutions Architect supporting Strategic Accounts. She supports customers as they look to secure and govern their AWS environment. Her enthusiasm for security drives her to continuously explore innovative ways to help customers protect their cloud workloads.

Summer 2025 SOC 1 report is now available with 183 services in scope

Post Syndicated from Tushar Jain original https://aws.amazon.com/blogs/security/summer-2025-soc-1report-is-now-available-with-183-services-in-scope/

Amazon Web Services (AWS) is pleased to announce that the Summer 2025 System and Organization Controls (SOC) 1 report is now available. The report covers 183 services over the 12-month period from July 1, 2024 to June 30, 2025, giving customers a full year of assurance. The reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.

Customers can download the Summer 2025 SOC 1 report through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.

To learn more about AWS compliance and security programs, see AWS Compliance Programs. As always, we value feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.


Tushar Jain

Tushar is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives Tushar holds a Master of Business Administration from Indian Institute of Management Shillong, India and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 13 years of experience in information security and holds CCSK and CSXF certifications.

Michael Murphy

Michael is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Michael has 12 years of experience in information security and holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

Atulsing Patil

Atulsing is a Compliance Program Manager at AWS and has 28 years of consulting experience in information technology and information security management. Atulsing holds a Master of Science in Electronics degree and professional certifications such as CCSP, CISSP, CISM, CDPSE, ISO 27001 Lead Auditor, HITRUST CSF, Archer Certified Consultant, and AWS CCP.

Nathan Samuel

Nathan is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Nathan has a Bachelor of Commerce degree from the University of the Witwatersrand, South Africa, and has over 21 years of experience in security assurance. He holds the CISA, CRISC, CGEIT, CISM, CDPSE, and Certified Internal Auditor certifications.

Gabby Iem

Gabby is a Program Manager at AWS. She supports multiple initiatives within AWS security assurance and has recently received her bachelor’s degree from Chapman University studying business administration.

Noah Miller

Noah is a Compliance Program Manager at AWS and supports multiple security and privacy initiatives within AWS. Noah has 6 years of experience in information security. He has a master’s degree in Cybersecurity Risk Management and a bachelor’s degree in Informatics from Indiana University.

Will Black

Will is a Compliance Program Manager at Amazon Web Services where he leads multiple security and compliance initiatives. Will has 10 years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he holds the CCSK and ISO 27001 Lead Implementer certifications.

Announcing cross-account ingestion for Amazon OpenSearch Service

Post Syndicated from David Venable original https://aws.amazon.com/blogs/big-data/announcing-cross-account-ingestion-for-amazon-opensearch-service/

Amazon OpenSearch Ingestion is a powerful data ingestion pipeline that AWS customers use for many different purposes, such as observability, analytics, and zero-ETL search. Many customers today push logs, traces, and metrics from their applications to OpenSearch Ingestion to store and analyze this data.

Today, we are happy to announce that OpenSearch Ingestion pipelines now support cross-account ingestion for push-based sources such as HTTP and OpenTelemetry (OTel). Organizations can now use this feature to effortlessly share data across teams. For example, many organizations have central observability teams—now these teams can create OpenSearch Ingestion pipelines and share them with other teams in their organization. You can also use this feature to ingest data into Amazon OpenSearch Service domains or Amazon OpenSearch Serverless collections in other accounts.

Previously, sharing OpenSearch Ingestion pipelines across accounts required teams to use virtual private cloud (VPC) features to share access. For example, teams could use VPC peering, which is not always feasible, or AWS Transit Gateway. The new cross-account ingestion features in OpenSearch Ingestion can simplify your deployment and reduce cost for sharing pipelines.

Solution overview

Let’s look at how to share a pipeline from a central logging account with two other development accounts (A and B). The central logging account can create an OpenSearch Ingestion pipeline using a push-based source, for example, HTTP. After creating the pipeline, a member of the central logging team can grant access to the other teams. They can use a resource policy that gives permissions to the two other team accounts to create pipeline endpoints. After making this change, the OpenSearch Ingestion pipeline is available for use by the other teams.

The following diagram illustrates this configuration.

In the following sections, we demonstrate how to implement this solution.

Prerequisites

First, the central logging account must have a VPC with two options enabled.

  • enableDnsSupport must be set to true
  • enableDnsHostnames must be set to true

The central logging account must also create a push-based OpenSearch Ingestion pipeline in the VPC. This can be a pipeline receiving logs from FluentBit or OpenTelemetry telemetry.

The development accounts that are going to connect to the pipeline also must have VPCs in the same region with the same DNS options enabled.

  • enableDnsSupport must be set to true
  • enableDnsHostnames must be set to true

Create resource policy

As the owner of the pipeline, you can create a resource policy that allows the two development accounts to create pipeline endpoints against your pipeline.

The following is an example resource policy for this scenario:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "AWS": [
          "000000000000",
          "999999999999"
        ]
      },
      "Action": "osis:CreatePipelineEndpoint",
      "Resource": "arn:aws:osis:us-west-2:123456789012:pipeline/central-logging"
    }
  ]
}

The OpenSearch Ingestion console makes it straightforward to create these policies, as shown in the following screenshot.

Create pipeline endpoint

Now that the central logging account has shared permissions on their pipeline, the development accounts can create pipeline endpoints. A pipeline endpoint is a connection from one VPC to an OpenSearch Ingestion pipeline.

The development accounts are responsible for creating the pipeline endpoints in the VPCs they want to connect from. They create this in the subnets they need and provide a security group. The security group should have an inbound rule allowing access port HTTPS over port 443 from any source that the development accounts need to ingest logs.

Development team A can create a pipeline endpoint using a command similar to the following:

aws --region us-west-2 osis create-pipeline-endpoint \
--pipeline-arn arn:aws:osis:us-west-2:123456789012:pipeline/central-logging \
--vpc-options '{"SubnetIds":["subnet-123456789012345678","subnet-012345678912345678"],"SecurityGroupIds":["sg-123456789012345678"]}'

Development team A can also use the OpenSearch Ingestion console to create the pipeline endpoint.

After performing this change, the VPC for development team A will have a pipeline endpoint. This pipeline endpoint now allows for ingesting data into the central logging pipeline. Now, Amazon Elastic Compute Cloud (Amazon EC2) instances, Amazon Elastic Container Service (Amazon ECS) tasks, Kubernetes pods, and other compute running in the VPC can ingest their log data into the pipeline using tools such as FluentBit.

At the same time or at a later time, development team B can create a pipeline endpoint as well. This team will create it for their own VPC.

After this, the pipeline will now have two pipeline endpoints, so both teams can ingest their log data into the central logging VPC.

Clean up

After a pipeline endpoint is created, either account can remove it. The development teams in our scenario can use the DeletePipelineEndpoint API to delete it from their accounts. Additionally, if the central logging account needs to remove a pipeline endpoint from a pipeline, it can use the RevokePipelineEndpointConnections API. Both options are available on the OpenSearch Ingestion console as well.

After the pipeline endpoints are removed, the central logging team can also remove the pipeline if they no longer need it.

Conclusion

The new pipeline endpoint feature for OpenSearch Ingestion simplifies how you can share pipelines for cross-account ingestion. This can help teams use the powerful features of OpenSearch Ingestion and open up new possibilities for teams or organizations using multiple accounts and VPCs. The new pipeline endpoint feature is available today in AWS Regions where OpenSearch Ingestion is available.

To get started with cross-account ingestion in OpenSearch Ingestion, refer to OpenSearch Ingestion documentation or try creating your first cross-account pipeline on the OpenSearch Ingestion console.


About the authors

David Venable

David Venable

David is a senior software engineer working on observability in OpenSearch at Amazon Web Services. He is a maintainer on the Data Prepper project.

Qwen models are now available in Amazon Bedrock

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/qwen-models-are-now-available-in-amazon-bedrock/

Today we are adding Qwen models from Alibaba in Amazon Bedrock. With this launch, Amazon Bedrock continues to expand model choice by adding access to Qwen3 open weight foundation models (FMs) in a full managed, serverless way. This release includes four models: Qwen3-Coder-480B-A35B-Instruct, Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B (Dense). Together, these models feature both mixture-of-experts (MoE) and dense architectures, providing flexible options for different application requirements.

Amazon Bedrock provides access to industry-leading FMs through a unified API without requiring infrastructure management. You can access models from multiple model providers, integrate models into your applications, and scale usage based on workload requirements. With Amazon Bedrock, customer data is never used to train the underlying models. With the addition of Qwen3 models, Amazon Bedrock offers even more options for use cases like:

  • Code generation and repository analysis with extended context understanding
  • Building agentic workflows that orchestrate multiple tools and APIs for business automation
  • Balancing AI costs and performance using hybrid thinking modes for adaptive reasoning

Qwen3 models in Amazon Bedrock
These four Qwen3 models are now available in Amazon Bedrock, each optimized for different performance and cost requirements:

  • Qwen3-Coder-480B-A35B-Instruct – This is a mixture-of-experts (MoE) model with 480B total parameters and 35B active parameters. It’s optimized for coding and agentic tasks and achieves strong results in benchmarks such as agentic coding, browser use, and tool use. These capabilities make it suitable for repository-scale code analysis and multistep workflow automation.
  • Qwen3-Coder-30B-A3B-Instruct – This is a MoE model with 30B total parameters and 3B active parameters. Specifically optimized for coding tasks and instruction-following scenarios, this model demonstrates strong performance in code generation, analysis, and debugging across multiple programming languages.
  • Qwen3-235B-A22B-Instruct-2507 – This is an instruction-tuned MoE model with 235B total parameters and 22B active parameters. It delivers competitive performance across coding, math, and general reasoning tasks, balancing capability with efficiency.
  • Qwen3-32B (Dense) – This is a dense model with 32B parameters. It is suitable for real-time or resource-constrained environments such as mobile devices and edge computing deployments where consistent performance is critical.

Architectural and functional features in Qwen3
The Qwen3 models introduce several architectural and functional features:

MoE compared with dense architectures – MoE models such as Qwen3-Coder-480B-A35B, Qwen3-Coder-30B-A3B-Instruct, and Qwen3-235B-A22B-Instruct-2507, activate only part of the parameters for each request, providing high performance with efficient inference. The dense Qwen3-32B activates all parameters, offering more consistent and predictable performance.

Agentic capabilities – Qwen3 models can handle multi-step reasoning and structured planning in one model invocation. They can generate outputs that call external tools or APIs when integrated into an agent framework. The models also maintain extended context across long sessions. In addition, they support tool calling to allow standardized communication with external environments.

Hybrid thinking modes – Qwen3 introduces a hybrid approach to problem-solving, which supports two modes: thinking and non-thinking. The thinking mode applies step-by-step reasoning before delivering the final answer. This is ideal for complex problems that require deeper thought. Whereas the non-thinking mode provides fast and near-instant responses for less complex tasks where speed is more important than depth. This helps developers manage performance and cost trade-offs more effectively.

Long-context handling – The Qwen3-Coder models support extended context windows, with up to 256K tokens natively and up to 1 million tokens with extrapolation methods. This allows the model to process entire repositories, large technical documents, or long conversational histories within a single task.

When to use each model
The four Qwen3 models serve distinct use cases. Qwen3-Coder-480B-A35B-Instruct is designed for complex software engineering scenarios. It’s suited for advanced code generation, long-context processing such as repository-level analysis, and integration with external tools. Qwen3-Coder-30B-A3B-Instruct is particularly effective for tasks such as code completion, refactoring, and answering programming-related queries. If you need versatile performance across multiple domains, Qwen3-235B-A22B-Instruct-2507 offers a balance, delivering strong general-purpose reasoning and instruction-following capabilities while leveraging the efficiency advantages of its MoE architecture. Qwen3-32B (Dense) is appropriate for scenarios where consistent performance, low latency, and cost optimization are important.

Getting started with Qwen models in Amazon Bedrock
To begin using Qwen models, in the Amazon Bedrock console, I choose Model Access from the Configure and learn section of the navigation pane. I then navigate to the Qwen models to request access. In the Chat/Text Playground section of the navigation pane, I can quickly test the new Qwen models with my prompts.

To integrate Qwen3 models into my applications, I can use any AWS SDKs. The AWS SDKs include access to the Amazon Bedrock InvokeModel and Converse API. I can also use these model with any agentic framework that supports Amazon Bedrock and deploy the agents using Amazon Bedrock AgentCore. For example, here’s the Python code of a simple agent with tool access built using Strands Agents:

from strands import Agent
from strands_tools import calculator

agent = Agent(
    model="qwen.qwen3-coder-480b-instruct-v1:0",
    tools=[calculator]
)

agent("Tell me the square root of 42 ^ 9")

with open("function.py", 'r') as f:
    my_function_code = f.read()

agent(f"Help me optimize this Python function for better performance:\n\n{my_function_code}")

Now available
Qwen models are available today in the following AWS Regions:

  • Qwen3-Coder-480B-A35B-Instruct is available in the US West (Oregon), Asia Pacific (Mumbai, Tokyo), and Europe (London, Stockholm) Regions.
  • Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B are available in the US East (N. Virginia), US West (Oregon), Asia Pacific (Mumbai, Tokyo), Europe (Ireland, London, Milan, Stockholm), and South America (São Paulo) Regions.

Check the full Region list for future updates. You can start testing and building immediately without infrastructure setup or capacity planning. To learn more, visit the Qwen in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Try Qwen models on the Amazon Bedrock console now, and offer feedback through AWS re:Post for Amazon Bedrock or your typical AWS Support channels.

— Danilo