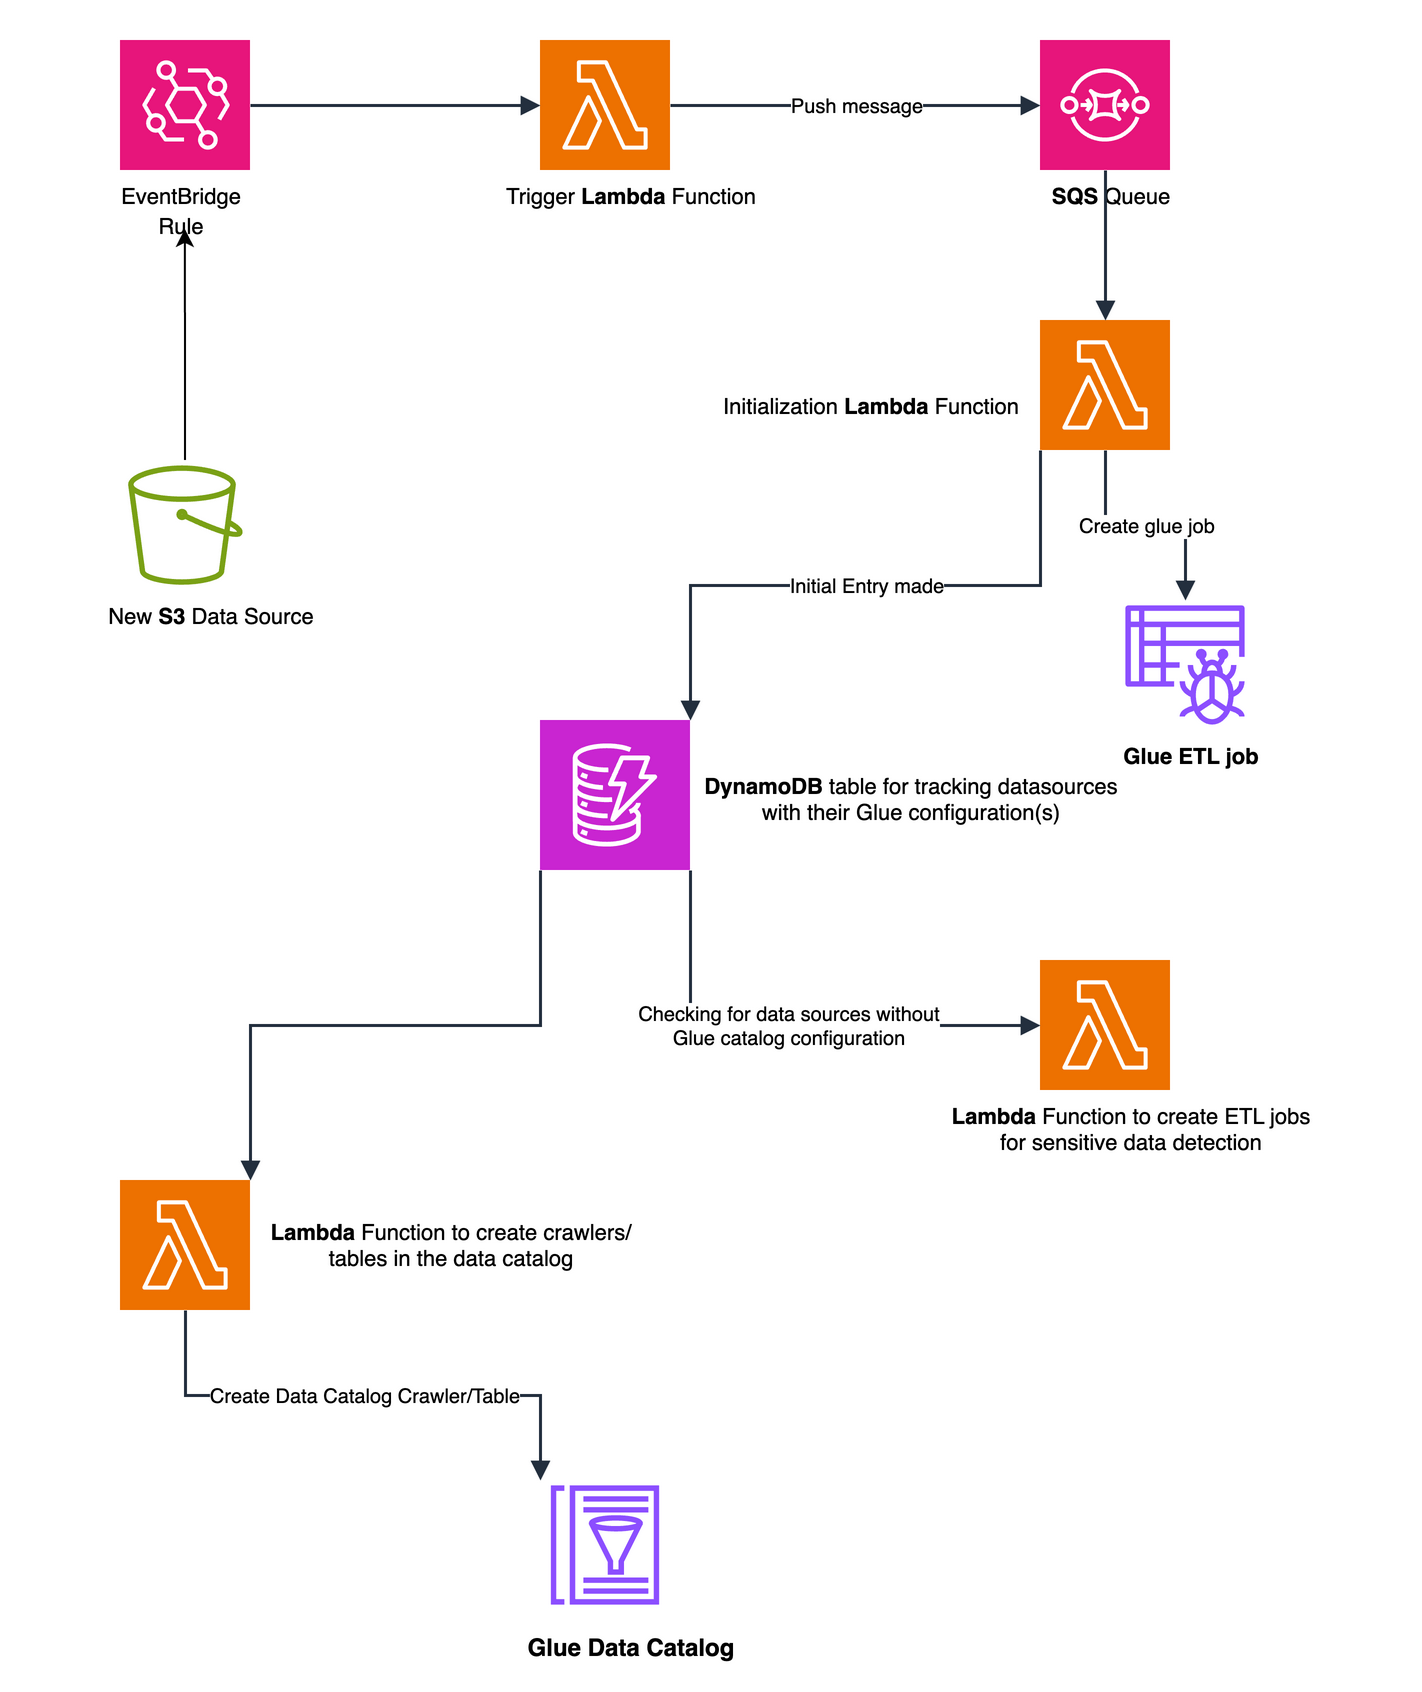
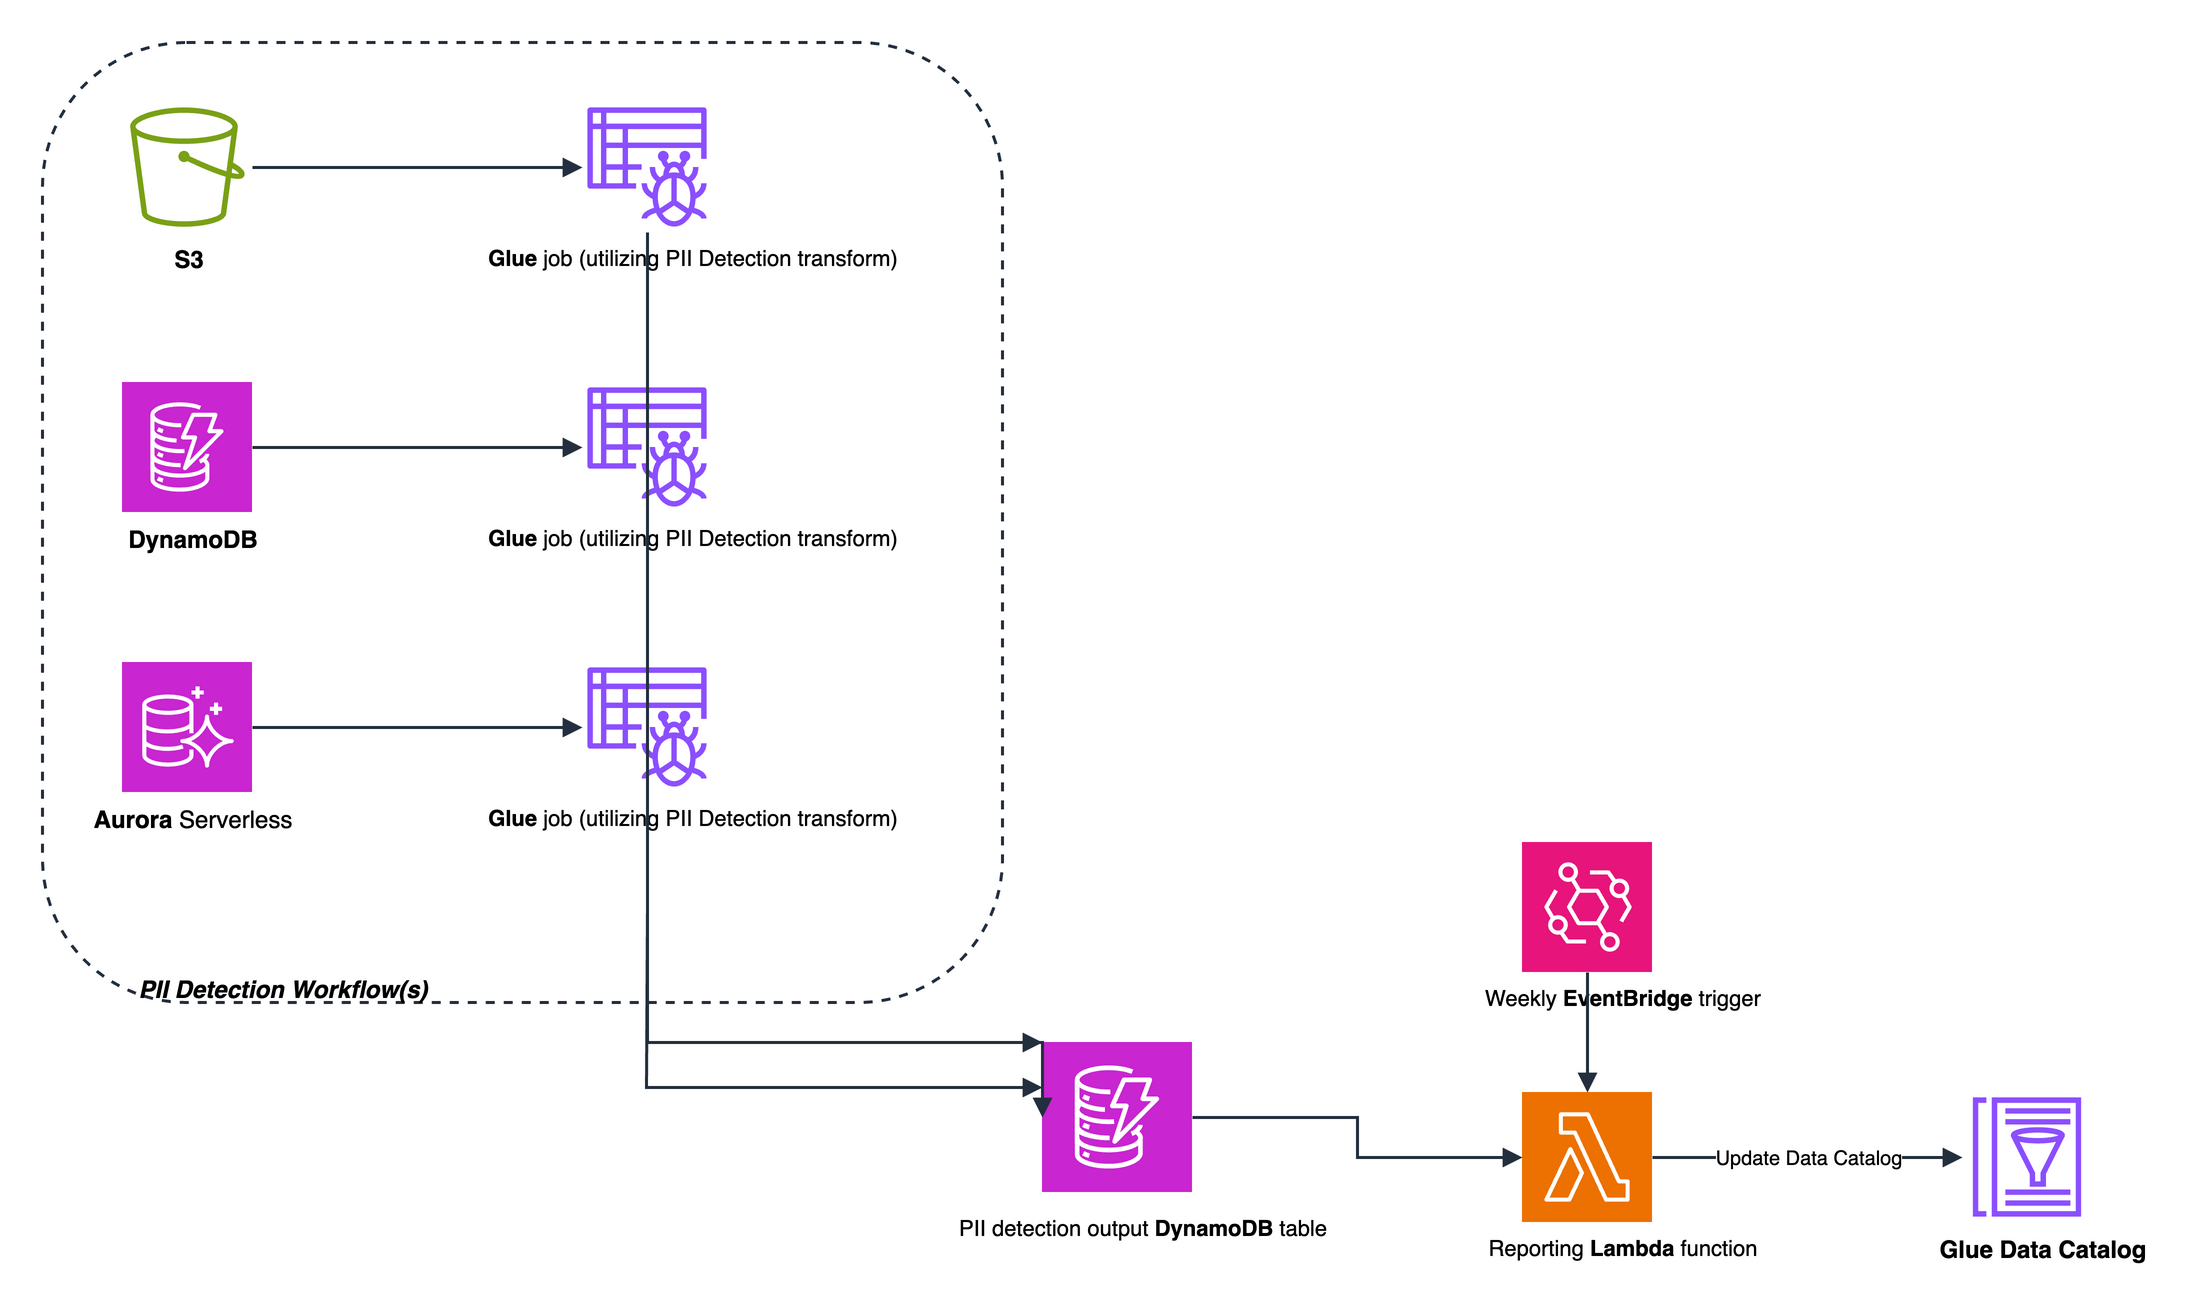
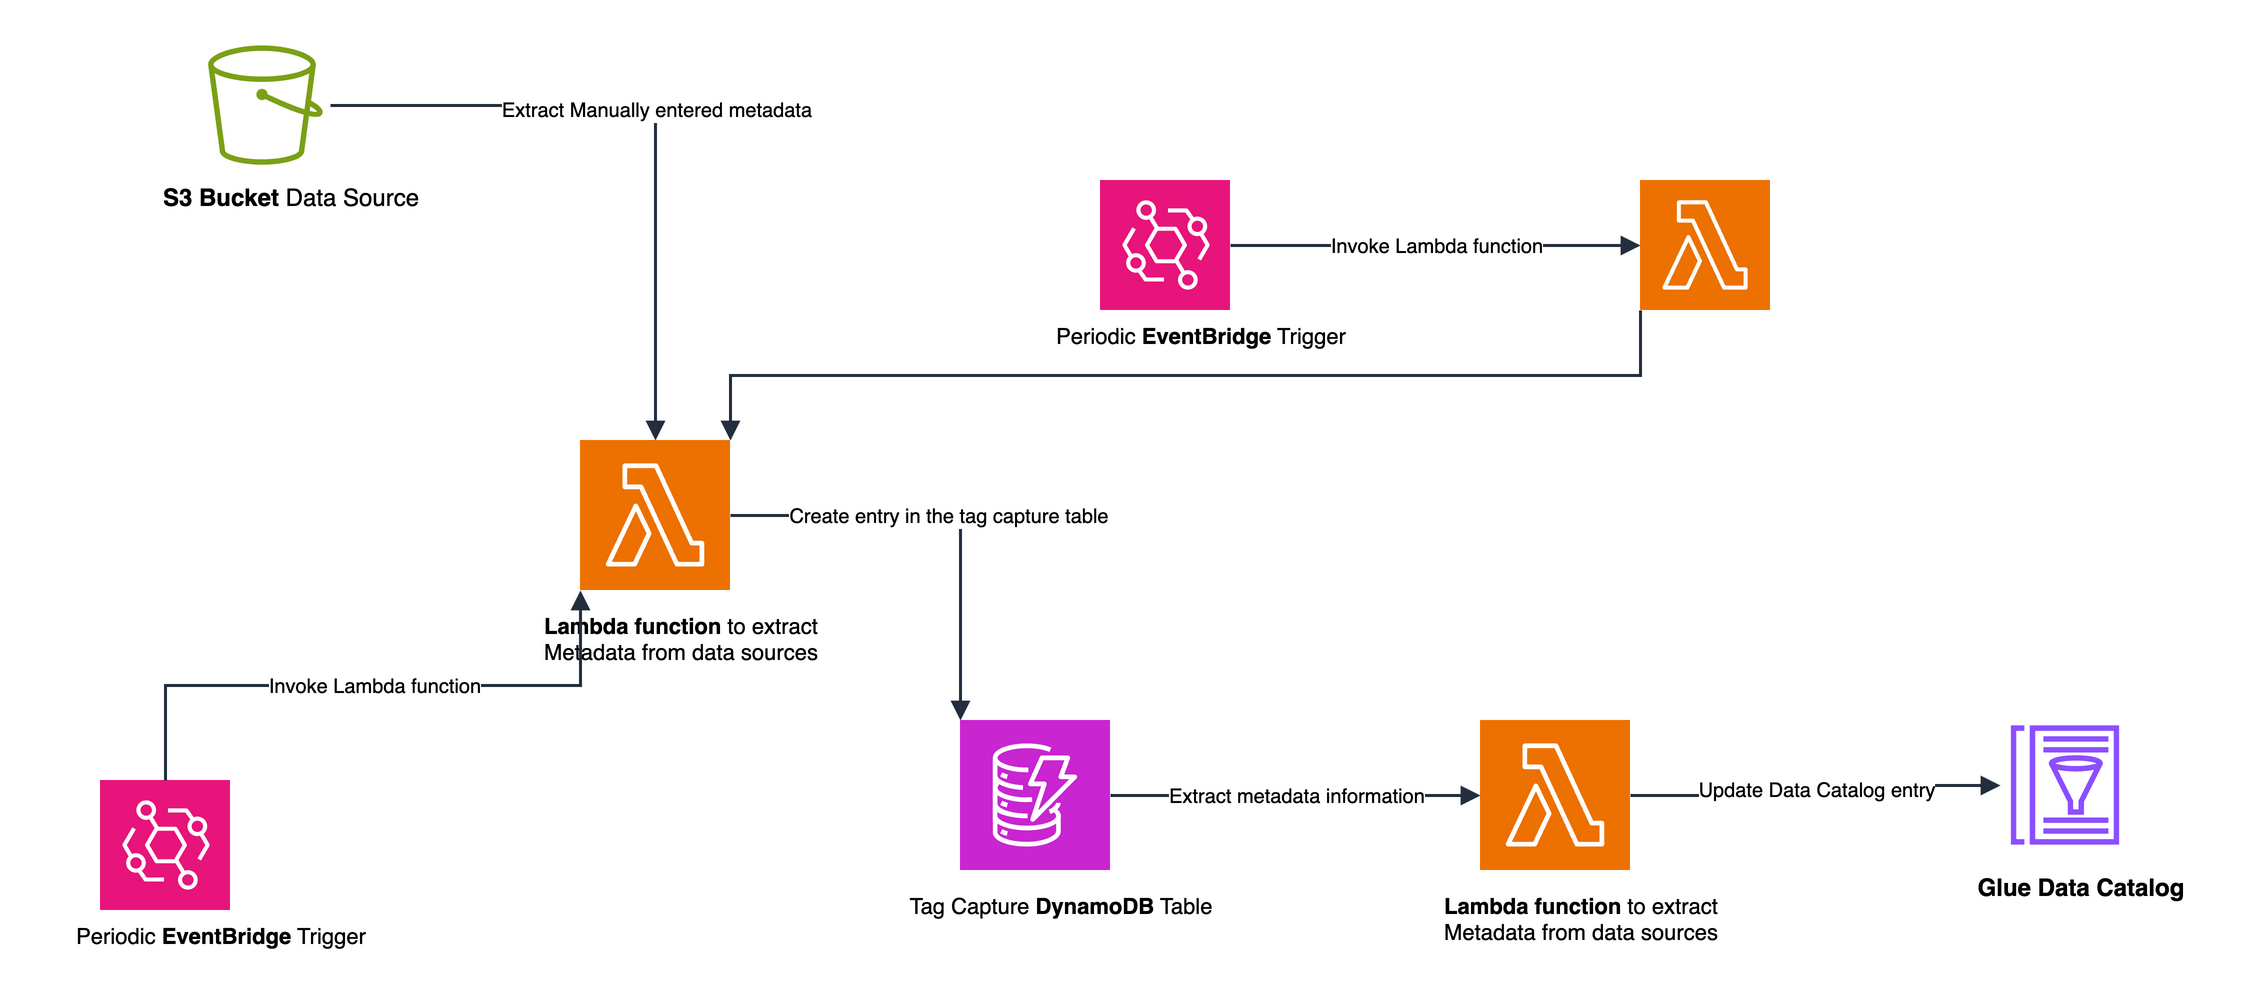
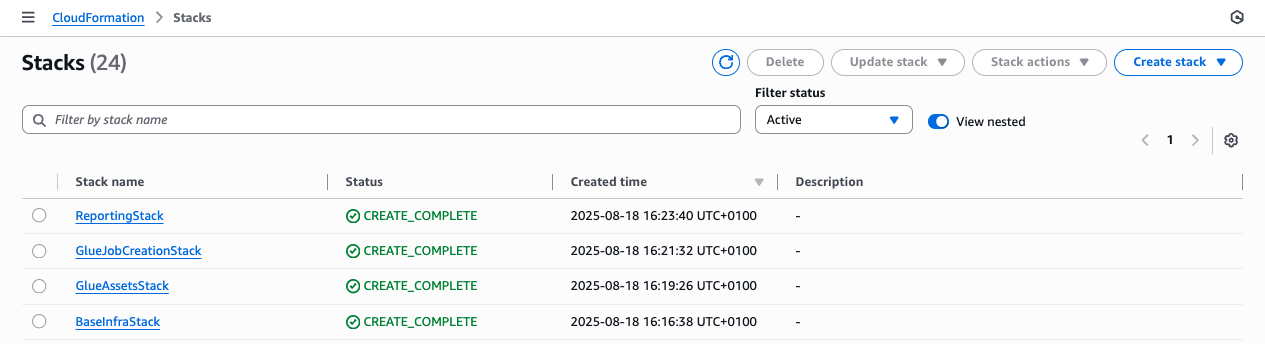
Data scientists and ML engineers often need to access raw data files in Amazon Simple Storage Service (Amazon S3) for machine learning training, data exploration, and generative AI workflows. However, when table-level access is governed by AWS Lake Formation, accessing the underlying S3 files has required maintaining separate permission mechanisms. S3 bucket policies or AWS Identity and Access Management (IAM) role policies create operational overhead and risk of permission drift.
Lake Formation now supports direct access to S3 data file locations for tables whose permissions it manages. Previously, data scientists with Lake Formation permissions on AWS Glue Data Catalog tables could query them using spark.sql(). Now, they can also read and write the underlying S3 data files using spark.read.parquet() or spark.read.csv() from Amazon EMR Spark jobs, Amazon SageMaker Unified Studio notebooks with EMR compute, and custom applications. All access is governed by the same Lake Formation permissions.
This capability is powered by the new GetTemporaryDataLocationCredentials() API, which vends temporary credentials scoped to registered S3 locations when callers have appropriate Lake Formation permissions on the corresponding Data Catalog tables. This eliminates the need to manage separate S3 bucket policies for file-level access while maintaining fine-grained access control in Lake Formation for table-based access. It enables your data scientists to explore S3 datasets securely, accelerate machine learning pipelines, and build generative AI workflows without compromising governance.
In this post, we demonstrate reading from and writing to Lake Formation-managed S3 locations using Apache Spark jobs from EMR. Lake Formation credential vending for S3 location access is available in EMR release label 7.13 and later, Boto3 1.42.29 and later, AWS Java SDK 2.41.32 and later, and AWS Command Line Interface (AWS CLI) version 2.33.1 and later.
Key use cases for Lake Formation permissions to S3 locations
Unified permissions for Analytics and Machine Learning pipelines – Data scientists can access both structured tables through SQL queries and underlying data files through programmatic APIs for machine learning and AI workloads. They are empowered to use tools of their choice – for example, use Amazon Athena for SQL analytics with the table names while read and write to the underlying files in their SageMaker notebook or Spark application with spark.read.parquet(“s3://bucket/database_path/table_files/).
Enable AI ready data lakes – Machine learning pipelines can read training data directly from governed data lakes. Generative AI applications can access foundation model training datasets, and data exploration workflows to use native file APIs while maintaining centralized governance and compliance.
Reduced operational complexity – Operations teams don’t need to maintain separate permission policies – one in Lake Formation for table access and another in S3 bucket policies or AWS Identity and Access Management (IAM) roles for file access. This reduces the risk of permission mismatches and avoids inconsistent access control.
Unified audit capability – Auditors do not need to examine multiple log sources, such as S3 Access Logs, AWS CloudTrail events from different services, to understand who accessed what data and when. With this feature, you get a unified CloudTrail audit trail showing both table access through SQL engines and file access through direct APIs, with each access event linked to the Lake Formation permission grant.
What customers are saying
“Through our close collaboration with AWS, Lake Formation’s new S3 location-based permissions have transformed how we manage data governance at Intuit. By unifying two separate access mechanisms for the same data into one unified permission model, we’ve dramatically reduced complexity and streamlined our auditing process. This is exactly the kind of simplification that lets our teams move faster without compromising security, ensuring we maintain the strict compliance and governance standards our regulators expect.”
— Tapan Upadhyay, Group Engineering Manager, Intuit
Lake Formation Credential Vending Plugin for AWS SDK v2 for Java
Lake Formation has made available a specialized library AWS Lake Formation Credential Vending Plugin for AWS SDK V2 for Java. The Java plugin intercepts S3 requests for data, checks Lake Formation permissions for the requested location, and provides temporary scoped credentials to the client if permissions are granted in Lake Formation. If the S3 location access permissions are not managed by Lake Formation, the plugin checks for access in Amazon S3 Access Grants and lastly falls back to IAM permissions. The plugin is supported independently of Spark and comes as an enhancement to EMR Spark Full Table Access (FTA) mode, starting in EMR 7.13 and later. The plugin is integrated at the S3A level. Therefore, any client of S3A can enable it by setting the S3A configurations, in addition to the EMR Lake Formation Full Table Access (FTA) configuration as follows:
With the Java plugin, you can enable governance for data lake resources in your custom applications with Lake Formation permissions – managing both fine grained access for users requiring restricted access on Data Catalog tables while providing direct S3 object level access to use-cases that require them.
Note: (1) The principal that will be accessing direct S3 locations of the tables will require full table access. That is, Lake Formation SELECT permission on all columns and rows of the table is required. (2) The Spark cluster needs FTA configuration. (3) Currently, Apache Iceberg table format is not supported with this plugin.
Solution overview
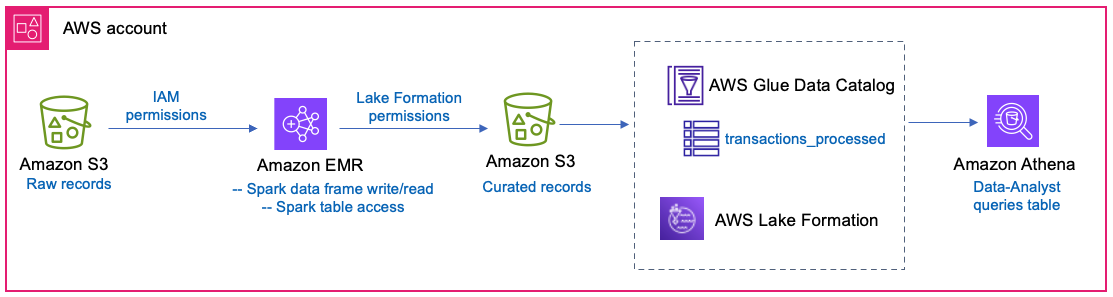
A financial services company runs daily ETL jobs using Spark in EMR. They process raw transaction records in S3 and store the processed records in another S3 location. The transformed Parquet data is registered with Lake Formation and cataloged as a table in Data Catalog. The ETL job will have direct IAM access to the raw data location, while it uses Lake Formation permissions to write to and read from the curated table location. Downstream, a data-analyst role will query the curated table, with restricted column access. The solution is shown in Figure 1.
Figure 1 – Architecture shows EMR Spark writing curated records to the S3 location of a table using Lake Formation permissions while Data-Analyst queries the same table with Lake Formation fine grained access control in Athena.
Prerequisites
To get started exploring this feature, we recommend you have the following setup.
To run the Spark code in EMR, you can choose to run the code in either SageMaker Unified Studio with EMR compute or use EMR cluster from EMR console. In the case of SageMaker Unified Studio domain and project, the Lake Formation permissions for the table location will be granted to the project execution role. In this post, we will illustrate using an EMR on EC2 cluster and a runtime role to submit the Spark script as a step to the cluster. For instructions to launch an EMR on EC2 cluster with Lake Formation full table access enabled, refer to instructions here – Lake Formation full table access for Amazon EMR on EC2 and Introducing runtime roles for Amazon EMR steps: Use IAM roles and AWS Lake Formation for access control with Amazon EMR. Fine Grained Access Control (FGAC) option is not supported for Spark on EMR with this feature since S3 location permission is full file path access.
First, we will get the setup ready with S3, sample database, table, and data. We will add a raw data set to S3 location, create a table with parquet data in another S3 location that represents the curated dataset for further downstream consumption. We will register the table data location with Lake Formation and grant permissions for the EMR run time role and Data-Analyst role.
Your S3 bucket will have the following structure.
Raw data – s3://<your-bucket-name>/raw/transactions/dt=2024-03-21/
Process data for table – s3://<your-bucket-name>/processed/transactions/
Spark script – s3://<your-bucket-name>/scripts/
Logs for the EMR cluster – s3://<your-bucket-name>/logs/
Step 1 – Create a parquet table in Data Catalog
From the Athena console query editor, create a table in Data Catalog.
-- Create a database
CREATE DATABASE finance_db;

-- Create an external table pointing to the S3 location
CREATE EXTERNAL TABLE IF NOT EXISTS finance_db.transactions_processed (
    transaction_id STRING,
    merchant_name STRING,
    amount DECIMAL(18,2),
    currency STRING,
    account_number STRING,
    card_type STRING,
    status STRING,
    region STRING
)
PARTITIONED BY (transaction_date DATE)
STORED AS PARQUET
LOCATION 's3:///processed/transactions/'
TBLPROPERTIES (
    'parquet.compress'='SNAPPY'
);
Step 2 – Register S3 location and grant table permission to IAM roles in Lake Formation
2.1 Register the table data location s3://<your-bucket-name>/processed/transactions/ with Lake Formation in Lake Formation mode using the custom S3 registration IAM role. For details on how to register locations with Lake Formation, refer Adding an Amazon S3 location to your data lake.
2.2 Grant DESCRIBE permission on the database finance_db and ALL permission on the table transactions_processed to your EMR runtime role.
2.3 Grant Data location permission to EMR runtime role on the curated table’s location. This is to allow writing to that location.
2.4 Grant DESCRIBE permission on the database finance_db and SELECT permission on the table transactions_processed to your Data-Analyst role. Exclude the columns transaction_id and account_number while granting SELECT permissions on the table to the Data-Analyst role.
3.2 Edit the S3 bucket name placeholder in the script (RAW_PATH and TABLE_PATH) to your resource names and upload to your S3 path s3://<your-bucket-name>/scripts/.
3.3 Make sure your EMR runtime role has access to the script location in its IAM policy permissions.
3.4 Submit and run the script as a step to the EMR cluster, following instructions at Add a Spark step.
What does the script do?
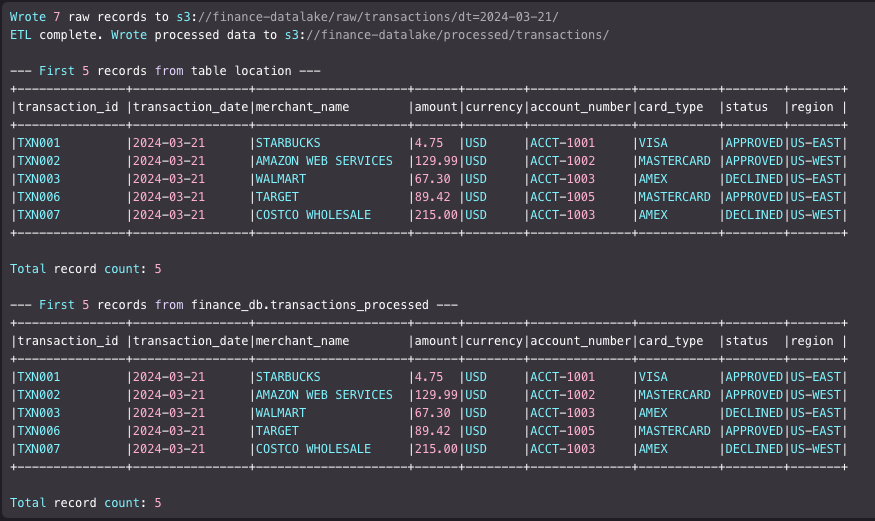
It populates raw records of transaction data into a Spark data frame, writes to the raw data bucket location using IAM permissions on the EMR runtime role. We apply some transformations and write directly to the S3 location of the table that is registered with Lake Formation, from the data frame using Spark’s native Parquet writer.
The following figure shows the stdout of the step.
The Java plugin integrated into EMR 7.13 automatically handles the access for the table’s data location registered with Lake Formation, so you don’t need to manually call the GetTemporaryDataLocationCredentials() API. In this example, the table data location s3://<your-bucket-name>/processed/transactions/ is registered with Lake Formation, for which EMR runtime role is granted ALL permissions. The direct S3 location access support by Lake Formation allows reading and writing to the location directly using Spark data frame.
Step 4 – Run query as Data-Analyst using Athena
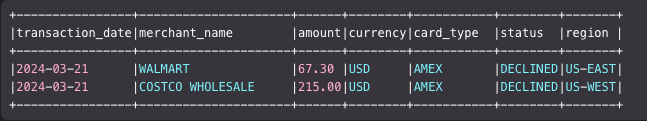
Log in as the Data-Analyst role to the Athena console. Run a select query on the table as follows.
SELECT * FROM finance_db.transactions_processed WHERE status = 'DECLINED' AND transaction_date=DATE '2024-03-21';
The Data-Analyst role should see all but two columns of the table.
With these steps complete, we’ve read from and written to direct S3 locations using Spark data frames with the syntax s3://bucketname/prefix/, and accessed the same data using database_name.table_name syntax with Lake Formation permissions. This shows fine-grained access at table level and coarse-grained access at the file path level.
Clean up
To avoid incurring costs, clean up the resources you created for this post.
Delete the Data Catalog database and tables. This removes the related Lake Formation permissions too. Remove the S3 bucket registration from Lake Formation.
Delete the data files, logs, and the PySpark script of this post from your S3 bucket.
Terminate the EMR cluster.
Conclusion
In this post, we showed how to use Lake Formation’s direct S3 location access to read and write data files using Spark data frames from Amazon EMR, while maintaining unified governance through Lake Formation permissions. We walked through the GetTemporaryDataLocationCredentials() API and the AWS Lake Formation Credential Vending Plugin for AWS SDK v2 for Java, which is integrated into EMR release labels 7.13 and later.
This capability unifies permission management for both fine-grained table-based access and direct S3 file path access in Lake Formation. Your data scientists can now use spark.read.parquet() and spark.write alongside spark.sql(), governed by the same permissions, audited in the same CloudTrail logs, and managed from a single console.
To get started, launch an EMR 7.13 cluster and start exploring the feature. Here are some additional resources:
Acknowledgements: We would like to thank all the team members who worked to launch this feature successfully – Rajas Bhate, Akhil Yendluri, Kunal Parikh, Sharda Khubchandani, Dhananjay Badaya, Santhosh Padmanabhan, Nitin Agrawal and Sandeep Adwankar.
In this post, we explore how to build an online shopping AI agent. We focus on its architecture and implementation with Amazon OpenSearch Service, Amazon Bedrock AgentCore, and Strands Agents. Amazon Bedrock AgentCore is an agentic platform for deploying and operating those agents and tools securely at scale without managing infrastructure. AgentCore Runtime is the secure, serverless runtime that hosts your Strands Agents and tools as containerized applications. Strands Agents is an open source SDK for building AI agents. In this SDK, an agent is defined by a model, tools, and a prompt. Tools are callable functions that allow agents to perform actions beyond text generation, such as API calls, database queries, and file operations. The framework lets the model autonomously plan steps and invoke tools to complete tasks.
Today’s AI shopping assistants understand natural language, context, and shopping intent, creating a more human-like interaction. These assistants handle complex shopping requirements, such as “Find me a formal dress under $200 that’s appropriate for a summer wedding.” They maintain conversation history, process follow-up questions naturally, and provide personalized recommendations based on user preferences and past interactions. Customers can use visual search to upload images of items that they want, and the AI finds similar products across multiple retailers, matching styles and patterns. The goal is to provide instant, relevant, and personalized assistance at scale, creating a more efficient shopping journey for consumers worldwide.
AI agents combined with Retrieval Augmented Generation (RAG) on Amazon OpenSearch Service represent an evolution in conversational search. This integration builds AI agents on enriched catalogs, supporting context-aware and autonomous search experiences while maintaining accuracy and relevance through grounded responses.
Solution overview
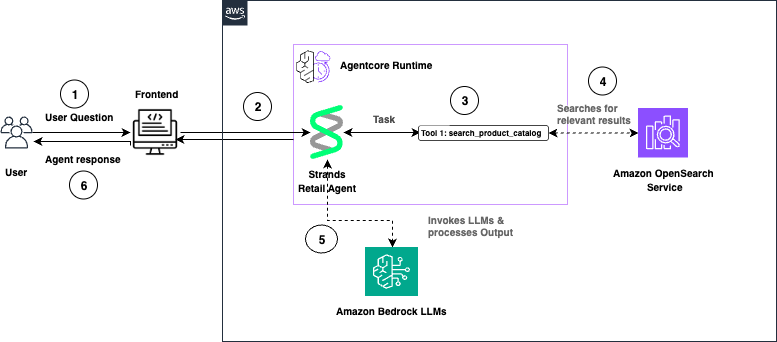
The following diagram illustrates the solution architecture of an AI-powered online shopping agent built using Strands Agents, Amazon Bedrock AgentCore Runtime, and Amazon OpenSearch Service. For simplicity, the diagram doesn’t show authentication and authorization. In a production setup, secure access to the backend by using mechanisms such as Amazon API Gateway, AWS Identity and Access Management (IAM) roles, or OAuth-based authentication.
The following is a walkthrough of the reference architecture:
The user submits a question through the front-end application. AgentCore Runtime receives the request and routes it to the Strands Retail Agent.
The Strands Agent processes the task and invokes the search_product_catalog tool.
OpenSearch Service performs semantic search and returns relevant product results.
The Strands Agent invokes Amazon Bedrock large language models (LLMs) to generate a natural language response.
The agent response is returned to the user through the front end.
Walkthrough
The following section walks you through how to build an online shopping AI agent.
Prerequisites
To implement this solution, you need an AWS account. You also need an OpenSearch Service domain with OpenSearch version 2.13 or later. You can use an existing domain or create a new domain.
To use the vector search capabilities of OpenSearch Service with Strands Agents on AgentCore, you use ingest pipelines. These ingestion pipelines apply built-in processors to pre-process your documents before you index them in OpenSearch Service.
You use the text_embedding processor, which relies on the ML Commons plugin and a registered embedding model—Amazon Nova Multimodal Embeddings on Amazon Bedrock. OpenSearch Service uses the ML Commons plugin to generate vector embedding for your data and uses the same model to convert incoming queries into vectors. This supports semantic search across your indexed content.
You extend your semantic search backend by adding an agent built with Strands Agents and deployed on Amazon Bedrock AgentCore.
Code samples provided in this post are tested in Python 3.11. You only need to install Python 3.11 in your environment to execute the python scripts. You also need Node.js 18 or later installed to use the AgentCore CLI. The provided code scripts will deploy into your AWS account so make sure your terminal has access to necessary AWS credentials.
Install AgentCore CLI
Install the AgentCore CLI globally using npm:
npm install -g @aws/agentcore
Python Dependencies
You also need to create a requirements.txt file with following dependencies in your workspace to deploy the agents.
Run pip install -r requirements.txt in your terminal to install the required dependencies. To avoid conflicts with other dependencies in your system, you can use a virtual environment.
Now, walk through each step.
Step 1: Configure IAM permissions
Complete the following steps to register the Nova Multimodal Embeddings model with OpenSearch Service and verify that your OpenSearch Service domain has permission to invoke the Amazon Bedrock API.
Go to the IAM console and create a new role with a custom trust policy. Add the following trust policy.
Give your role a name and create it. For this post, we use OpenSearchBedrockEmbeddingRole as the role name. OpenSearch Service uses this role to invoke the Nova Multimodal Embeddings model on Amazon Bedrock.
On the Permissions tab, attach an inline policy with the following permissions. For this post, we name this policy OpenSearchBedrockEmbeddingPolicy.
Create a passRole policy with the following JSON document and assign it to the IAM role that creates the ML connector. This lets the principal running the Python code pass the OpenSearchBedrockEmbeddingRole to OpenSearch. Replace <your-aws-account-id> with your own AWS account ID.
By using fine-grained access control (FGAC), map the IAM role as a backend role for the ml_full_access role in the OpenSearch Dashboards Security plugin. This mapping lets the user create ML connectors:
Log in to OpenSearch Dashboards and open the Security page from the navigation menu.
Choose Roles and select ml_full_access.
Choose Mapped Users and Manage Mapping.
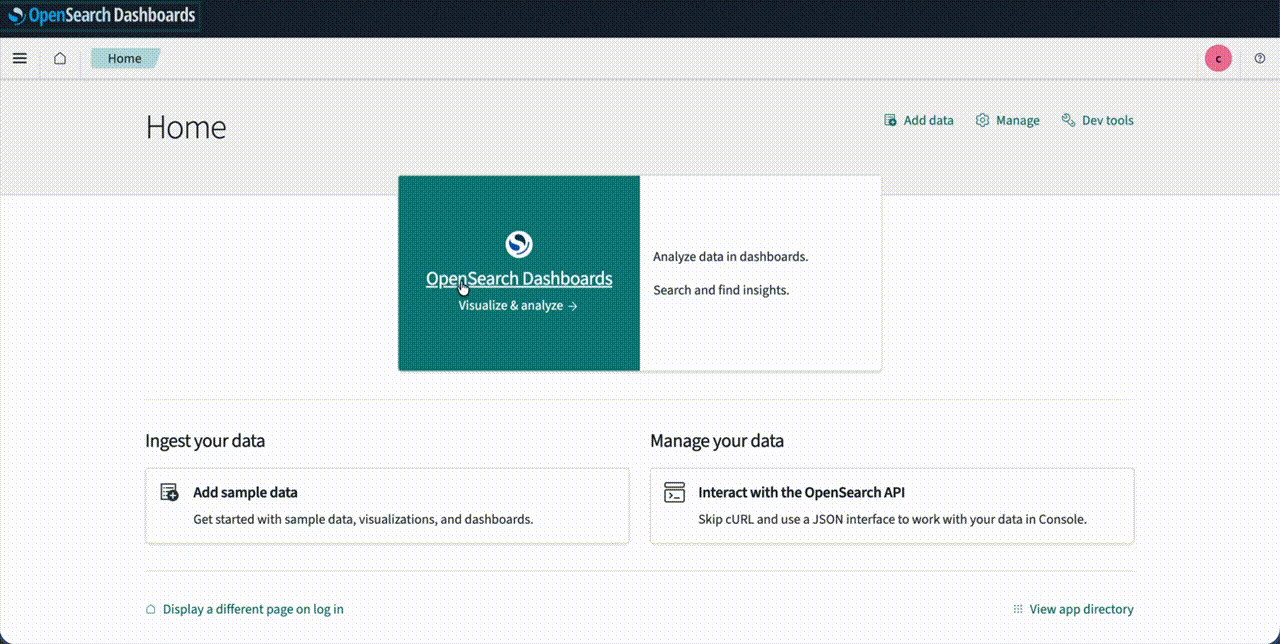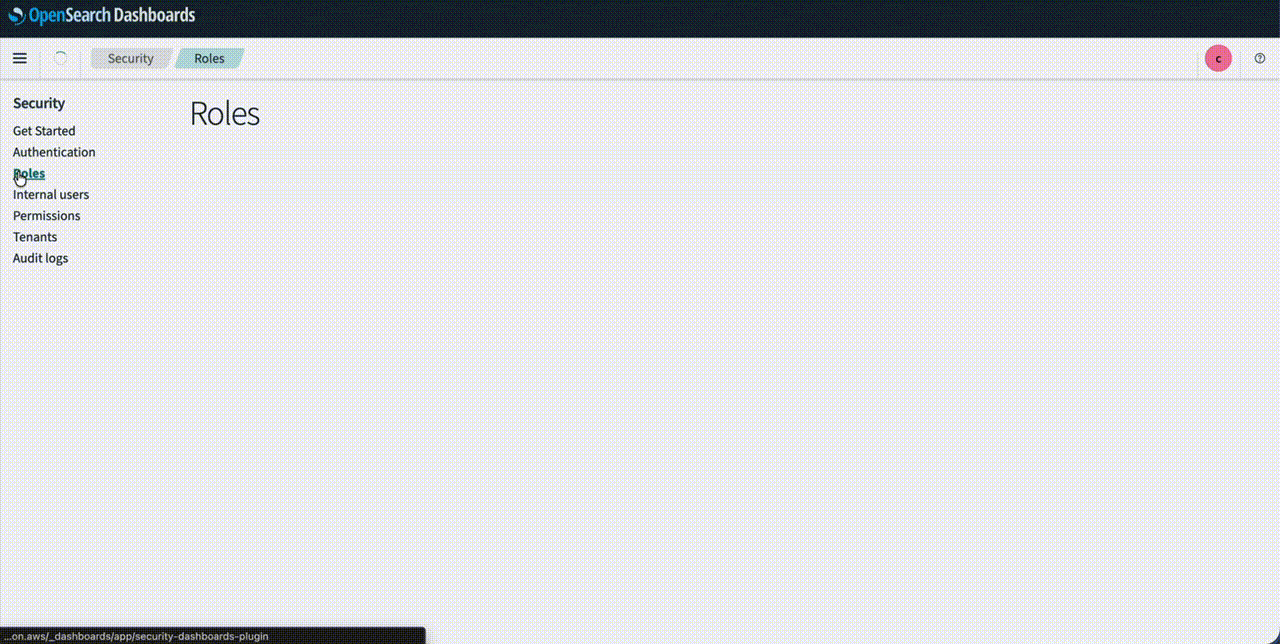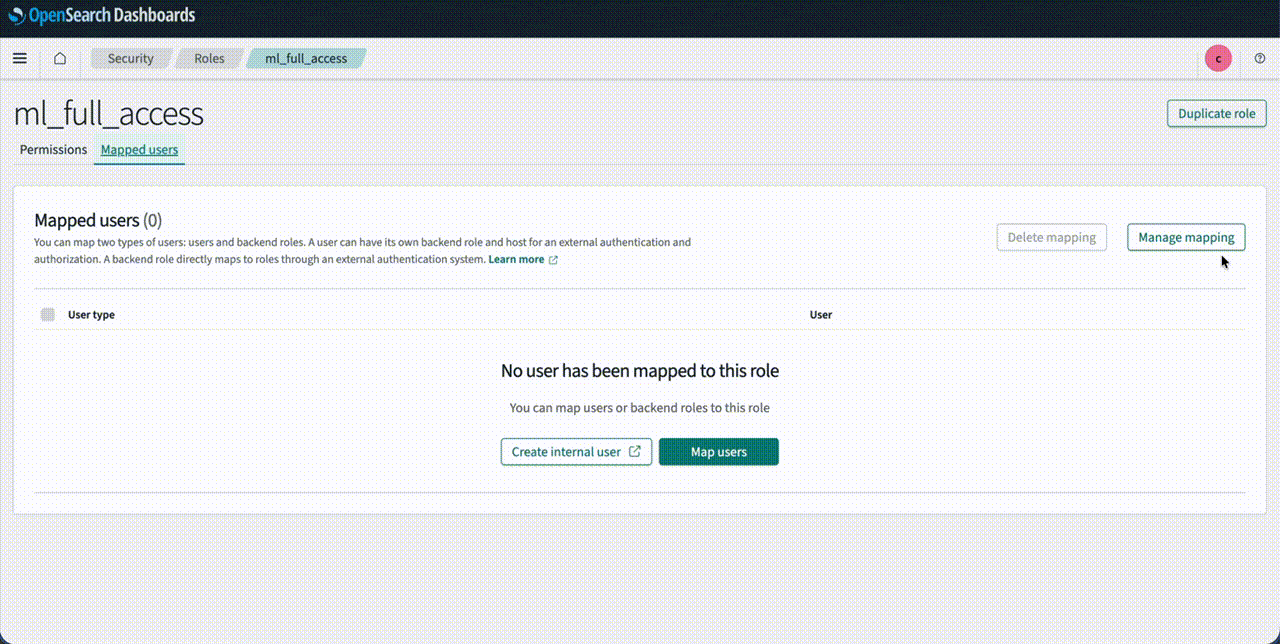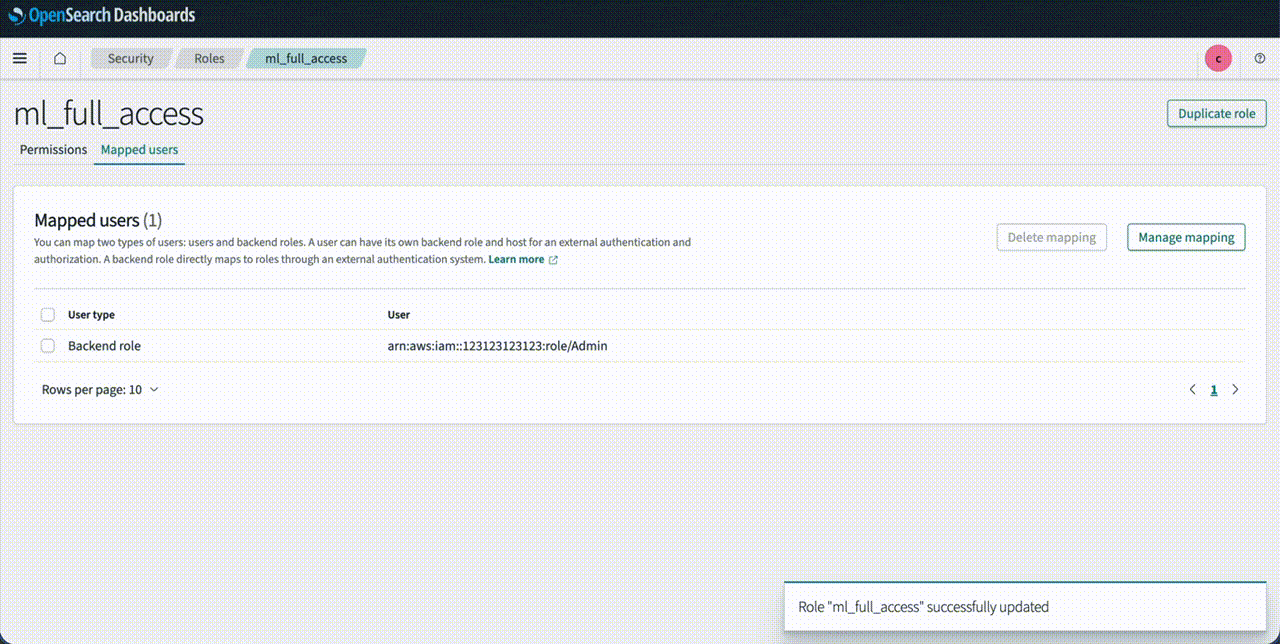
Under Backend roles, add the ARN of the IAM role that you created in the previous steps.
Step 2: Connect to the model by using OpenSearch ML Connectors
In this section, you create an ML connector to link OpenSearch Service with the Bedrock Nova Multimodal Embeddings model. You then register and deploy the model so you can use it for neural search queries.
Create a file named create-connector.py with the following code. Replace <your hostname>, <your region>, and <your account id> placeholders within the code.
Run python create-connector.py in your terminal by using the IAM role with ml_full_access and passRole permissions created in the previous step. This script creates a connector between OpenSearch Service and the Bedrock Nova Multimodal Embeddings model.
The program responds with connector_id. Take a note of it. Then, navigate to OpenSearch Dashboards and open Dev Tools. Create a model group against which to register this model in the OpenSearch Service domain.
POST /_plugins/_ml/model_groups/_register
{
  "name": "agent-conversational-search-model-group",
  "description": "A model group for bedrock Nova embedding models used for conversational search"
}
Register a model by using connector_id and model_group_id.
Run the following API call to deploy the model. Use the registered model ID from the previous step.
POST /_plugins/_ml/models/<registered-model-id>/_deploy
Step 3: Create an ingest pipeline for data indexing
Use the following code to create an ingest pipeline for data indexing. The pipeline establishes a connection to the embedding model, retrieves the embedding for the title field, and stores it in the OpenSearch index.
PUT /_ingest/pipeline/nova_multimodal_embedding
{
  "description": "Text embedding pipeline using nova_multimodal_embedding",
  "processors": [
    {
      "text_embedding": {
        "model_id": "<deployed model id>",
        "field_map": {
          "title": "title_vector"
        }
      }
    }
  ]
}
Step 4: Create an index for storing data
Create an index named product for storing data by using Dev Tools. This index stores raw text and 1024-dimensional embeddings of the title field, and uses the ingest pipeline you created in the previous step.
Use the following code to ingest the sample product data in Dev Tools.
POST /_bulk
{"index": {"_index": "product", "_id": "2"}}
{"id":2,"title":"Mens Casual Premium Slim Fit T-Shirts","price":22.3,"description":"Slim-fitting style, contrast raglan long sleeve, three-button henley placket, light weight & soft fabric for breathable and comfortable wearing.","category":"men's clothing","image":"https://fakestoreapi.com/img/71-3HjGNDUL._AC_SY879._SX._UX._SY._UY_.jpg","rating":{"rate":4.1,"count":259}}
{"index": {"_index": "product", "_id": "3"}}
{"id":3,"title":"Mens Cotton Jacket","price":55.99,"description":"great outerwear jackets for Spring/Autumn/Winter, suitable for many occasions, such as working, hiking, camping, mountain/rock climbing, cycling, traveling or other outdoors.","category":"men's clothing","image":"https://fakestoreapi.com/img/71li-ujtlUL._AC_UX679_.jpg","rating":{"rate":4.7,"count":500}}
{"index": {"_index": "product", "_id": "4"}}
{"id":4,"title":"Mens Casual Slim Fit","price":15.99,"description":"The color could be slightly different between on the screen and in practice.","category":"men's clothing","image":"https://fakestoreapi.com/img/71YXzeOuslL._AC_UY879_.jpg","rating":{"rate":2.1,"count":430}}
{"index": {"_index": "product", "_id": "5"}}
{"id":5,"title":"John Hardy Women's Legends Naga Gold & Silver Dragon Station Chain Bracelet","price":695,"description":"From our Legends Collection, the Naga was inspired by the mythical water dragon that protects the ocean's pearl.","category":"jewelery","image":"https://fakestoreapi.com/img/71pWzhdJNwL._AC_UL640_QL65_ML3_.jpg","rating":{"rate":4.6,"count":400}}
Step 6: Query the index
Run the following API call to test semantic search by using the Nova Multimodal Embeddings model.
Import the Runtime app with from bedrock_agentcore.runtime import BedrockAgentCoreApp.
Initialize the app in your code with app = BedrockAgentCoreApp().
Create the OpenSearch Service connection and search query with the @tool decorator.
Decorate the invocation function with the @app.entrypoint decorator.
Let AgentCore Runtime control the running of the agent with app.run().
Now, complete the following steps:
Make sure that you have installed the necessary dependencies from the Prerequisites section of this post.
Create and save a file named search_agent.py with the following code. Replace <your hostname>, <your region>, and <your account id> placeholders within the code.
from strands import Agent, tool
import argparse
import json
from bedrock_agentcore.runtime import BedrockAgentCoreApp
from strands.models import BedrockModel
import boto3
from opensearchpy import OpenSearch, RequestsHttpConnection
from requests_aws4auth import AWS4Auth
app = BedrockAgentCoreApp()
@tool
def search_products(query: str, size: int = 5):
try:
# OpenSearch configuration
host = '' ## CHANGE THIS, DOMAIN ENDPOINT WITHOUT HTTPS!
region = '' ##CHANGE THIS
model_id= '' ##CHANGE THIS with your deployed model id in OpenSearch
service = 'es'
credentials = boto3.Session().get_credentials()
awsauth = AWS4Auth(credentials.access_key, credentials.secret_key, region, service, session_token=credentials.token)
# Create OpenSearch client
client = OpenSearch(
hosts=[{'host': host, 'port': 443}],
http_auth=awsauth,
use_ssl=True,
verify_certs=True,
connection_class=RequestsHttpConnection
)
"""Search products in OpenSearch using neural search"""
search_body = {
"_source": False,
"fields": ["title", "price", "category", "image"],
"size": size,
"query": {
"neural": {
"title_vector": {
"query_text": query,
"model_id": model_id,
"k": 3
}
}
}
}
response = client.search(
body=search_body,
index="product"
)
products = []
for hit in response['hits']['hits']:
fields = hit.get('fields', {})
product = {
'title': fields.get('title', [''])[0] if fields.get('title') else '',
'price': fields.get('price', [''])[0] if fields.get('price') else '',
'category': fields.get('category', [''])[0] if fields.get('category') else '',
'image': fields.get('image', [''])[0] if fields.get('image') else ''
}
products.append(product)
return f"Found {len(products)} products: {json.dumps(products, indent=2)}"
except Exception as e:
return f"Search error: {str(e)}"
model_id = "global.anthropic.claude-haiku-4-5-20251001-v1:0"
model = BedrockModel(
model_id=model_id,
)
agent = Agent(
model=model,
tools=[search_products],
system_prompt="You're a helpful assistant. You can do product search, and tell the product details."
)
@app.entrypoint
def strands_agent_bedrock(payload):
"""
Invoke the agent with a payload
"""
user_input = payload.get("prompt")
print("User input:", user_input)
response = agent(user_input)
return response.message['content'][0]['text']
if __name__ == "__main__":
#strands_agent_bedrock({"prompt": "Search jacket"}) ##UNCOMMENT THIS FOR TESTING
#app.run() ##UNCOMMENT THIS FOR DEPLOYMENT, MAKE SURE THE ABOVE LINE IS COMMENTED WHEN YOU ARE DEPLOYING TO AGENTCORE
This deploys your agent locally for testing purposes.
Navigate to the IAM console and add the AmazonBedrockLimitedAccess permission policy to the principal running the code.
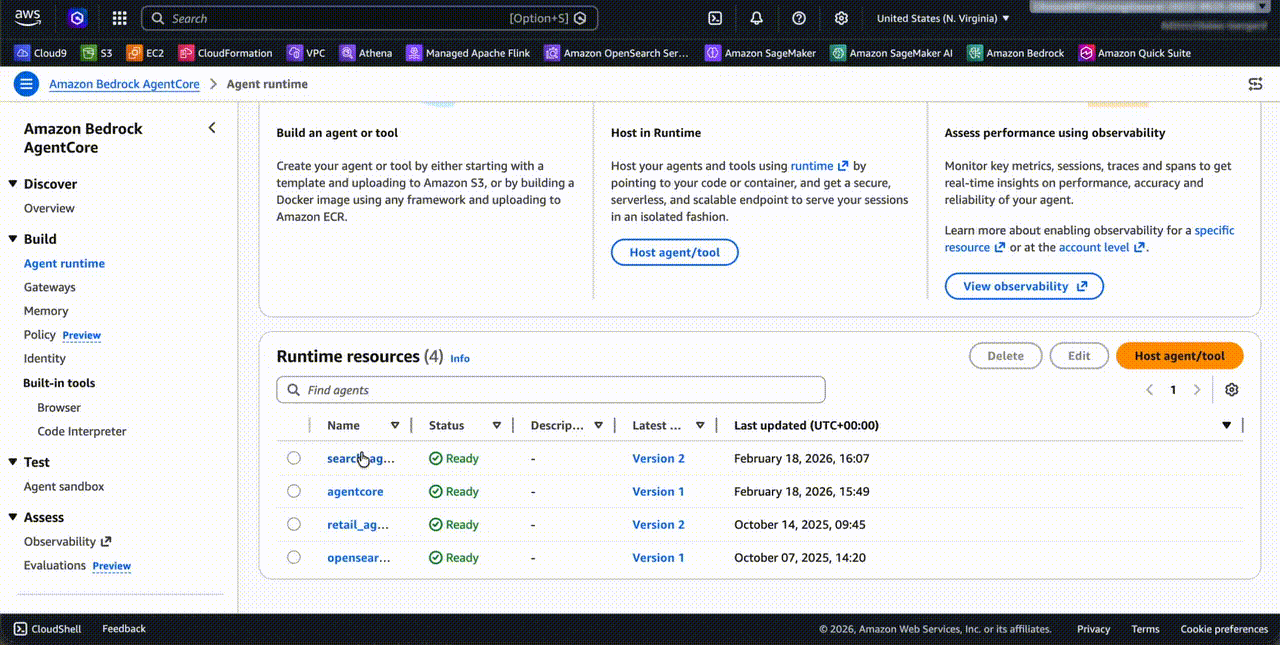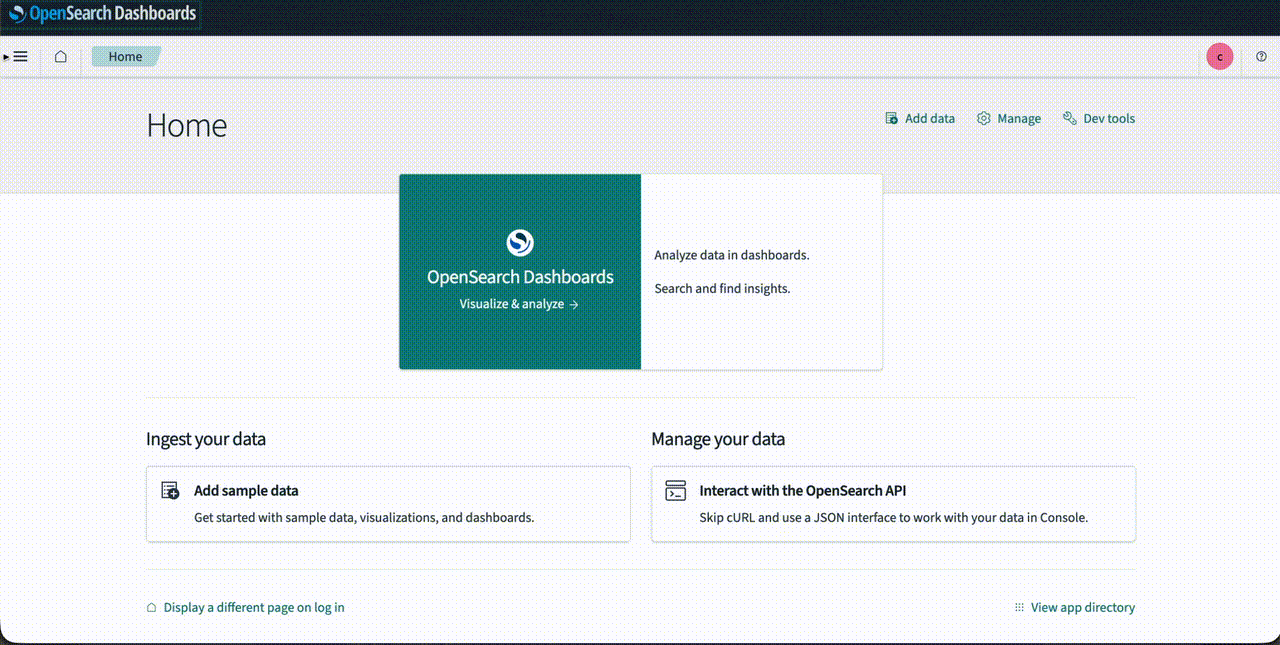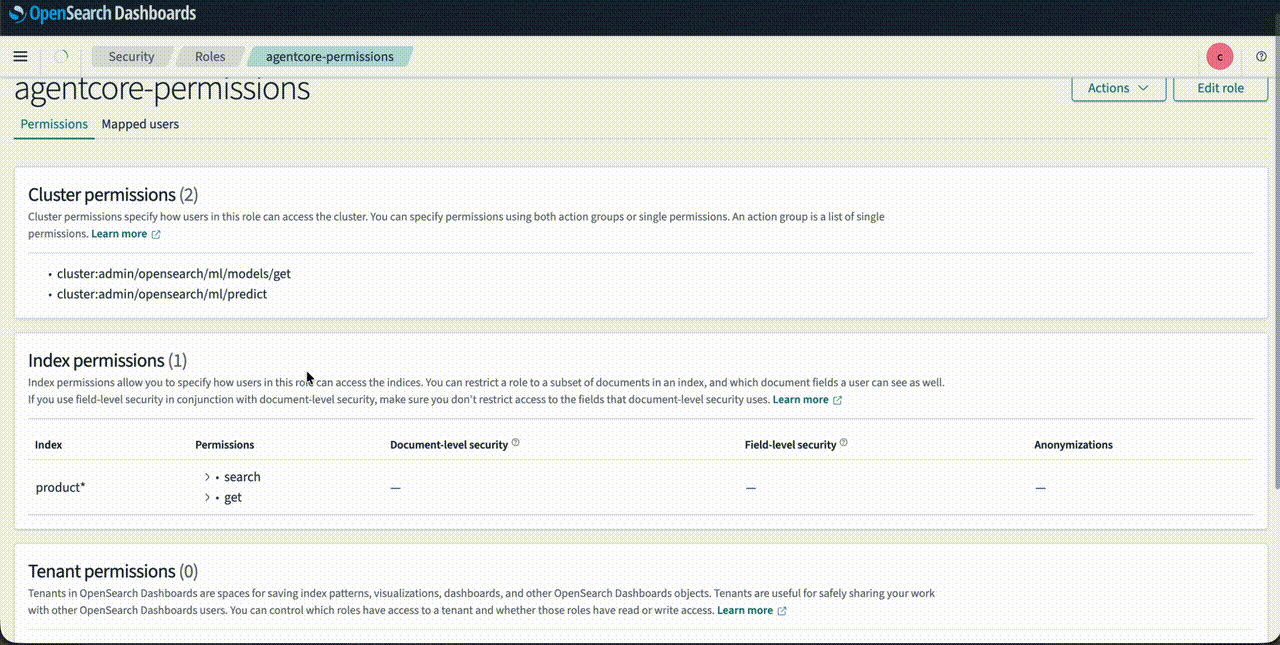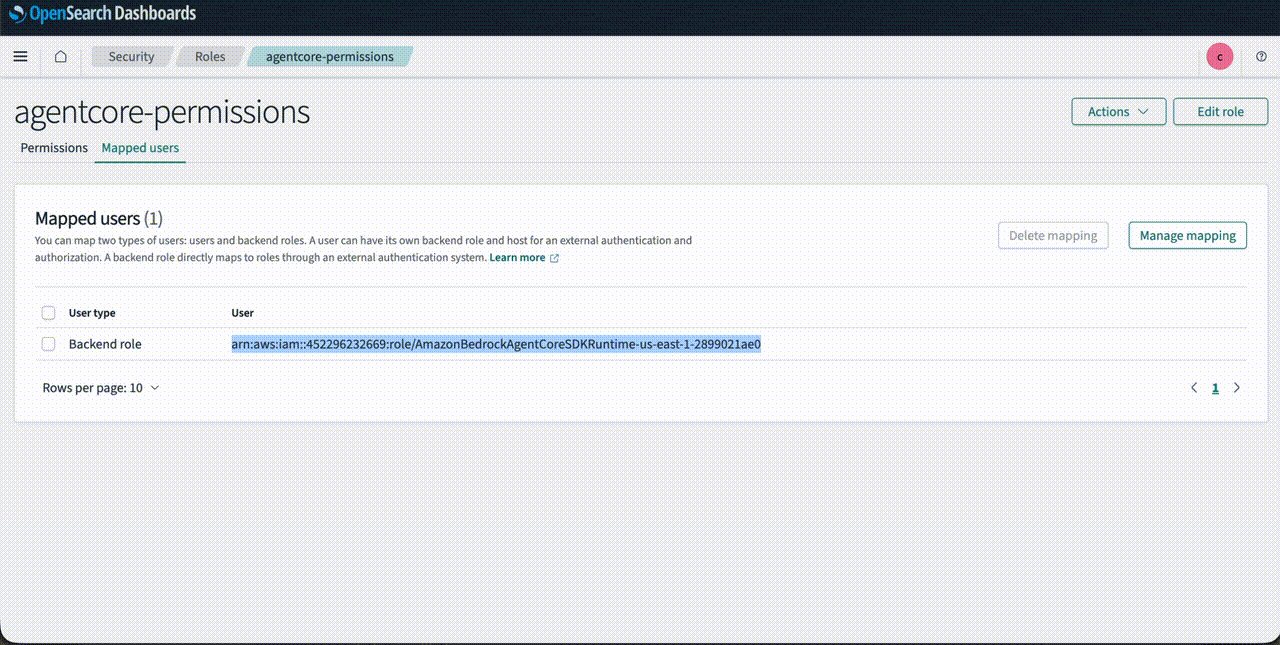
Navigate to OpenSearch Dashboards and, from the left menu, choose Security plugin, then choose Roles.
Choose Create Role.
Name the role agentcore-permissions.
Under cluster permissions, add cluster:admin/opensearch/ml/models/get and cluster:admin/opensearch/ml/predict.
Under index permissions, enter product* as the index pattern. Add search and get permissions.
Create the role.
Choose the role you created, switch to the Mapped Users tab, choose Manage mapping, and add the role that you use for running the Python code as a backend role.
Uncomment the line strands_agent_bedrock({"prompt": "Search jacket"}) and make sure the app.run() line is commented in the code.
Run python search_agent.py in your terminal to start the shopping agent. The output should look similar to the following.
"Here are the jacket search results:\n\n1. **Mens Cotton Jacket** - $55.99\n2. **Mens Casual Slim Fit** - $15.99\n3. **Mens Casual Premium Slim Fit T-Shirts** - $22.30\n4. **John Hardy Women's Legends Naga Gold & Silver Dragon Station Chain Bracelet** - $695.00\n\nThe most relevant jacket option is the **Mens Cotton Jacket** at $55.99. Would you like to know more about any of these products?
Comment strands_agent_bedrock({"prompt": "Search jacket"}) and uncomment the app.run() line in the code before going into the next step.
Step 8: Configure and launch your agent to Bedrock AgentCore Runtime
The AgentCore CLI is a command-line tool provided by AWS that simplifies deployment of agents to Amazon Bedrock AgentCore Runtime. When you run the CLI deployment command, it automates the entire deployment workflow: it creates the necessary IAM execution role with proper permissions, packages your Python application code along with its dependencies, uses AWS CodeBuild to build an optimized Docker container image, pushes that container image to Amazon Elastic Container Registry (ECR), and finally provisions the AgentCore Runtime environment that hosts your containerized agent. This eliminates the need for manual Dockerfile creation, container builds, or infrastructure management.
Before you start this step, make sure you have gone through section 7 and installed the AgentCore CLI and Python dependencies listed in the Prerequisites section.
Create a policy named AgentCoreAccessPolicy with the following permissions and attach it to the role running the code. Replace <ACCOUNT_ID> and <REGION> placeholders.
Create a file named agentcore.yaml in your project directory with the following configuration. Replace <REGION>, <ACCOUNT_ID>, and <OPENSEARCH_DOMAIN_NAME> placeholders:
Map your AgentCore execution role to an OpenSearch backend role so the agent can access your data.
Navigate to OpenSearch Dashboards. From the left menu, choose the Security plugin, then choose Roles.
Search for agentcore-permissions and choose the role. Then, navigate to the Mapped Users tab, choose Manage mapping, and add arn:aws:iam::<ACCOUNT_ID>:role/AmazonBedrockAgentCoreSDKRuntime-us-east-1-custom as a backend role. Replace the <ACCOUNT_ID> placeholder with your account ID.
Step 10: Invoke the Bedrock AgentCore Runtime
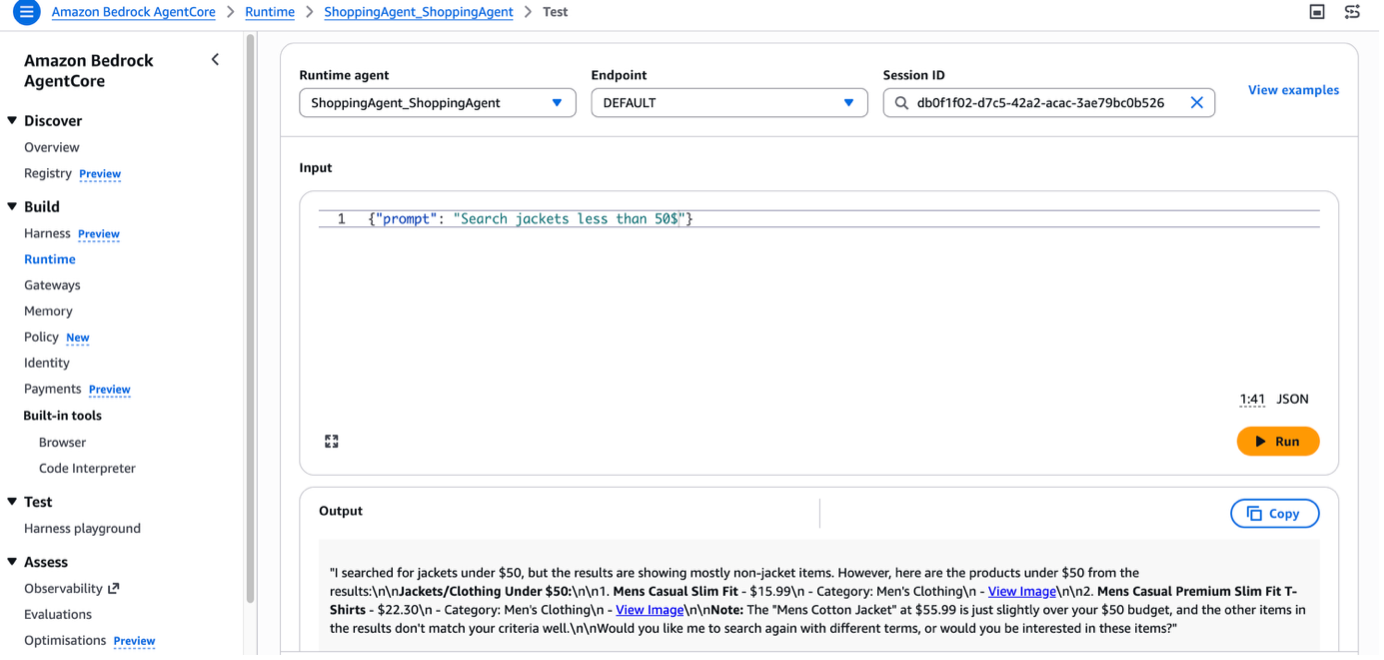
You can test the agent in Agent Sandbox. Enter the prompt Search jacket less than 50$, and the agent returns the relevant result from the OpenSearch Service index with a summary.
In real-world scenarios, you can design a search application with a Strands Agent deployed in AgentCore Runtime. You can add AgentCore Memory, which gives your AI agents the ability to remember past interactions and provide more context-aware, personalized conversations.
Cleanup
To avoid incurring future charges, delete the resources created while building this solution:
In this post, you saw how to create a conversational search with Amazon OpenSearch Service and Strands Agents. You also learned how to deploy the agent on Amazon Bedrock AgentCore Runtime. You can further enhance this shopping agent by using other AgentCore capabilities. For example, AgentCore Memory retains user preferences and past interactions across sessions, AgentCore Identity manages shopper authentication and access control, and AgentCore Observability helps you monitor and debug agent behavior in production. Together, these services help you build shopping experiences that deliver instant, relevant assistance at scale.
Now it’s your turn. Build your own conversational search experience by integrating OpenSearch Service and Strands Agents with your product catalog. To learn more, see the Amazon OpenSearch Service and Amazon Bedrock AgentCore detail pages.
Whether you’re processing financial data, managing e-commerce orders, or training machine learning (ML) models, efficiently coordinating complex processes is essential. Amazon Web Services (AWS) offers two services for workflow orchestration: Amazon Managed Workflows for Apache Airflow (Amazon MWAA) and AWS Step Functions.
This post explores how to select the right workflow orchestration service based on your specific use case requirements. We’ll examine key workflow characteristics, present real-world scenarios, and provide practical guidance to help you make an informed decision for your particular needs.
Understanding workflow orchestration requirements
Before exploring specific services, consider the key dimensions that influence workflow orchestration needs:
Data statefulness: Does your workflow process independent units of work (stateless) or create dependencies where each step modifies data from previous steps (stateful)?
Execution duration: Are your workflows short-lived (seconds to minutes) or long-running (hours to days)?
Scheduling requirements: Do you need built-in time-based execution or rely primarily on event triggers?
Recovery capabilities: How critical is the ability to restart from specific failure points rather than reprocessing entirely?
Integration complexity: What systems, services, and data sources need to be coordinated?
Security and access control: Do you need fine-grained permissions for different workflow components?
Let’s explore how these requirements map to real-world use cases and the appropriate orchestration solutions.
Use case: Enterprise data analytics pipeline
This scenario illustrates how Amazon MWAA handles complex, stateful data pipelines with built-in scheduling and granular recovery.
Business challenge
A global financial services company processes massive volumes of transaction data daily, requiring sophisticated data analytics capabilities. Their requirements include:
Designed to process 5-10 TB of financial transaction data daily
Running complex extract, transform, and load (ETL) jobs with multiple transformation stages
Generating regulatory reports for compliance use cases
Supporting both scheduled batch processing and event-driven workflows
Capable of handling long-running jobs that can take up to 12 hours
Ensuring data consistency and integrity throughout the pipeline
Workflow characteristics
Data statefulness: Highly stateful workflows where each processing step modifies transaction data, creating dependencies throughout the pipeline
Scheduling needs: Mixed time-based and event-driven patterns
Recovery requirements: Critical ability to resume from specific failure points
Integration complexity: Orchestrates multiple AWS services and external systems
Solution: Amazon Managed Workflows for Apache Airflow (Amazon MWAA)
For this enterprise data analytics scenario, Amazon MWAA provides capabilities that align well with these requirements:
Stateful workflow management
MWAA excels at managing complex, stateful data pipelines where data consistency is critical. When processing terabytes of financial data, MWAA’s ability to resume from the last successful checkpoint helps prevent costly reprocessing and maintain data integrity.
The following code example demonstrates how to structure a complex financial ETL pipeline in MWAA:
# Example: Complex ETL pipeline with proper dependency management
from airflow import DAG
from airflow.operators.python_operator import PythonOperator
from datetime import datetime, timedelta

dag = DAG(
	'financial_etl_pipeline',
	schedule_interval='0 2 * * *',  # Daily at 2 AM
	start_date=datetime(2024, 1, 1),
	catchup=False
)

# Define tasks
extract_transactions = PythonOperator(task_id='extract_transactions', ...)
extract_market_data = PythonOperator(task_id='extract_market_data', ...)
transform_data = PythonOperator(task_id='transform_data', ...)
load_warehouse = PythonOperator(task_id='load_warehouse', ...)
generate_reports = PythonOperator(task_id='generate_reports', ...)

# Express complex dependencies clearly
[extract_transactions, extract_market_data] >> transform_data >> [load_warehouse, generate_reports]
This Directed Acyclic Graph (DAG) shows how to define task dependencies for parallel data extraction followed by sequential transformation and loading operations. The >> operator clearly defines the workflow dependencies. Transformation only begins after both extraction tasks complete successfully.
Built-in scheduling capabilities
MWAA includes native scheduling capabilities, making it straightforward to set up recurring workflows without additional services. The schedule_interval parameter in the DAG definition provides flexible scheduling options using cron syntax.
Granular recovery and resume control
During production incidents, operations teams can use the MWAA web interface to restart or bypass specific steps with a few clicks. This capability is important for stateful applications where restarting the entire workflow could compromise data consistency.
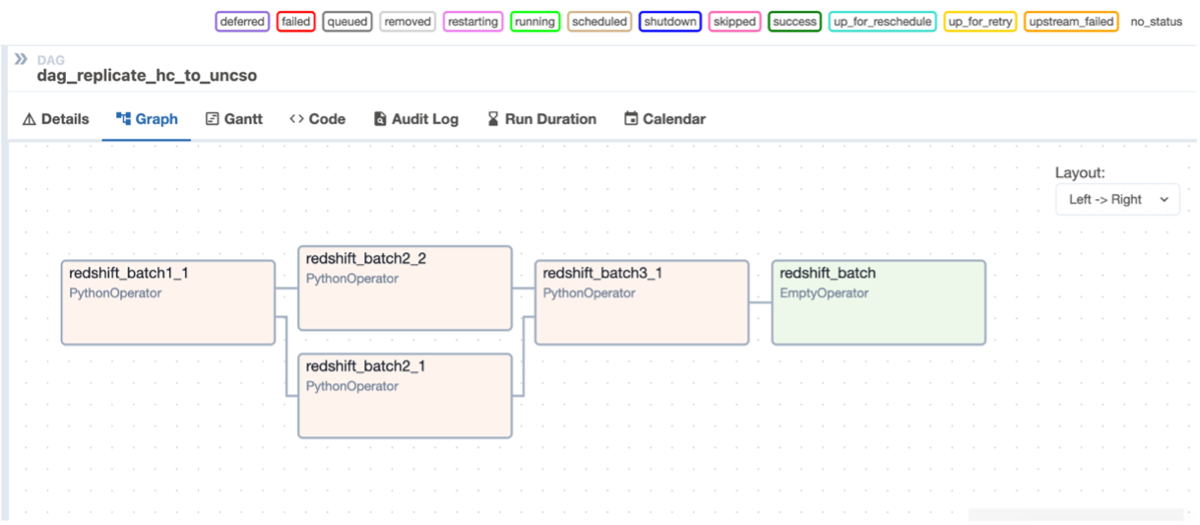
The MWAA web interface provides a visual representation of the workflow execution, allowing operators to:
Identify failed tasks – Examine task logs for troubleshooting – Clear the status of specific tasks – Restart execution from specific points
Figure 1: A Directed Acyclic Graph (DAG) in MWAA showing parallel execution ofAmazon Redshift Data APItasks. If any task fails, you can re-run specific tasks rather than restarting from the beginning.
Infrastructure planning: While MWAA requires capacity planning, the automatic scaling capabilities effectively handle variable workloads by setting minimum and maximum worker counts.
Security model: MWAA uses a shared execution role across DAGs, but you can implement additional security through resource-level policies and separate environments for different teams.
Cost predictability: The worker-hour pricing model provides predictable costs for long-running jobs, making budget planning more straightforward.
Use case: Real-time serverless application orchestration
This scenario shows how AWS Step Functions handles event-driven, serverless workflows that need to scale automatically with unpredictable traffic.
Business challenge
An e-commerce platform needs to orchestrate real-time order processing workflows that can handle thousands of concurrent orders during peak shopping periods. Their requirements include:
Designed for processing customer orders in real-time (targeting sub-second response times)
Coordinating payment validation, inventory checks, and fulfillment
For this real-time e-commerce scenario, AWS Step Functions provides capabilities that align well with these requirements:
Serverless architecture and automatic scaling
Step Functions automatically scales to handle traffic spikes without infrastructure management. During peak shopping events like Black Friday, the service handles increased load without manual intervention.
Event-driven workflow execution
Step Functions is designed for order-triggered workflows that need immediate execution. The following JSON definition shows how to structure an e-commerce order processing workflow:
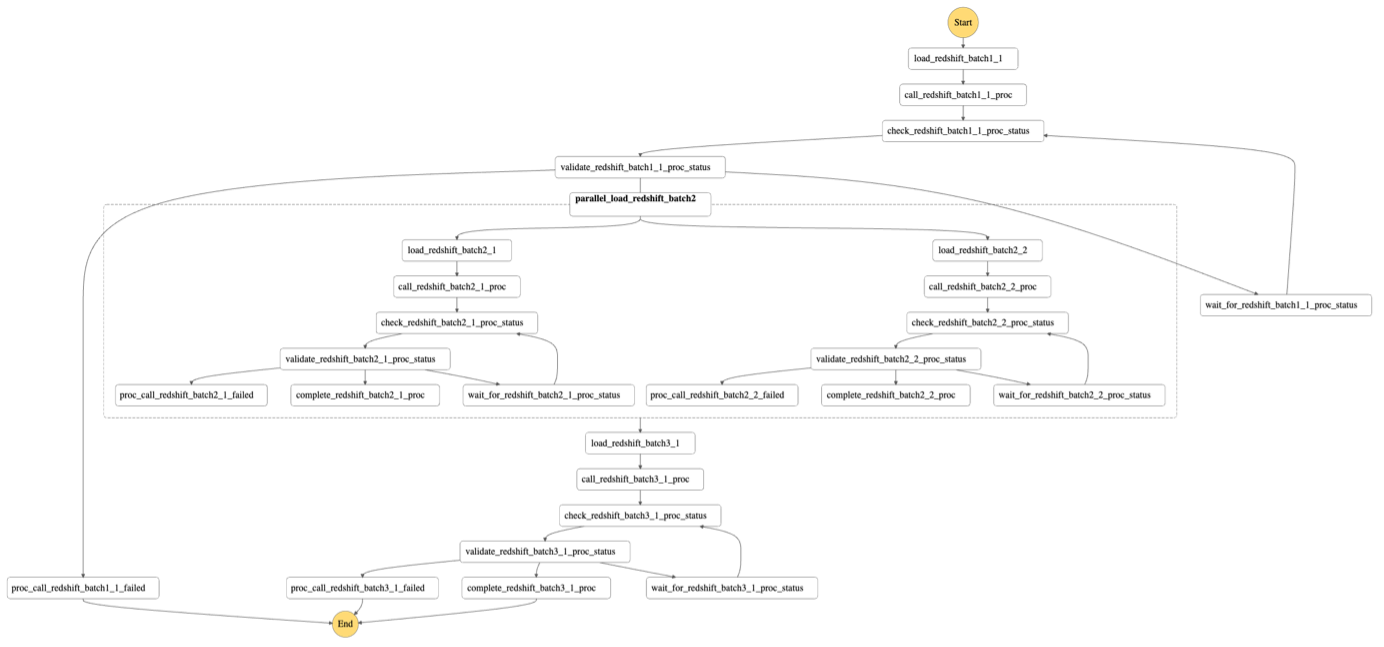
This Step Functions definition demonstrates several key capabilities: – The ValidatePayment state includes built-in retry logic with exponential backoff – The CheckInventory state uses parallel execution to simultaneously check multiple warehouses – Each Lambda function is called via its Amazon Resource Name (ARN), providing direct integration with AWS services
Figure 2: A complex workflow in AWS Step Functions, involving multiple stages of data processing. The parallel execution doesn’t allow resuming from a specific mid-execution step, but the branching structure provides automated error handling and recovery.
Native AWS service integration
Step Functions provides direct integration with Lambda functions, SQS queues, SNS topics, and DynamoDB, eliminating the need for custom connectors or additional infrastructure components.
Cost-effective pay-per-use model
The pay-per-execution pricing model aligns with variable order volumes, keeping costs minimal during slow periods while scaling automatically during busy times.
Human approval workflow support
Step Functions supports human approval steps, making it suitable for high-value order workflows that require manual review or approval processes.
Implementation considerations
Error handling: Built-in retry mechanisms and error handling patterns help provide reliable order processing with configurable retry policies.
Visual monitoring: The Step Functions console provides real-time visibility into order processing status, enabling quick identification of bottlenecks.
Security model: Fine-grained AWS Identity and Access Management (IAM) roles per step so that payment processing functions have different permissions than inventory management functions.
Choosing the right workflow orchestration service
When selecting between Amazon MWAA and AWS Step Functions, consider these workflow characteristics:
Consider Amazon MWAA when your use case involves:
Complex stateful data processing where workflows modify data state and require recovery mechanisms to maintain consistency
Long-running batch jobs executing for hours or days where computational investment is substantial
Built-in scheduling requirements where regular batch processing needs time-based orchestration
Granular recovery needs where resuming from specific failure points is business-critical
Complex task dependencies involving sophisticated relationships between workflow tasks
Existing Apache Airflow expertise where teams have substantial investment in Apache Airflow knowledge
Consider AWS Step Functions when your use case involves:
Event-driven serverless workflows triggered by external events requiring immediate response
Stateless processing where each workflow execution operates independently
Short to medium duration tasks completing within minutes to hours
Heavy AWS service integration involving extensive coordination with Lambda functions and other AWS services
Human approval workflows requiring manual intervention or decision-making
Variable load patterns with unpredictable traffic requiring automatic scaling
Decision framework
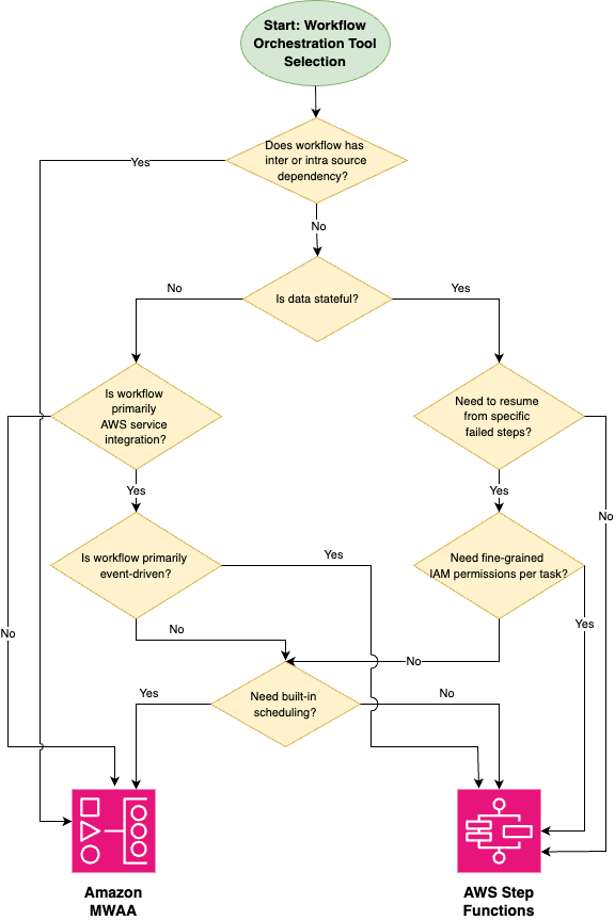
To help guide your decision process, consider the following questions:
Figure 3: Decision tree guiding through key considerations for choosing between Amazon MWAA and AWS Step Functions based on workflow characteristics.
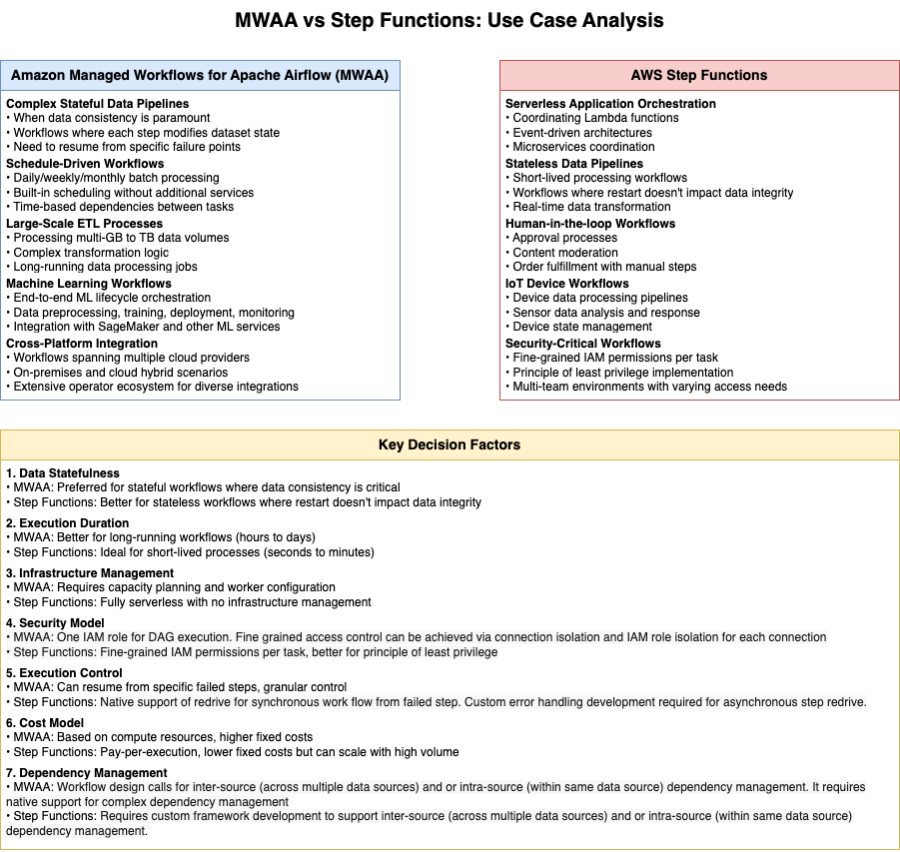
Figure 4: Comprehensive comparison between Amazon MWAA and AWS Step Functions, highlighting decision factors for choosing the right workflow orchestration service.
Conclusion
Both Amazon Managed Workflows for Apache Airflow and AWS Step Functions are workflow orchestration services, each designed to address specific use case requirements. By understanding your workflow characteristics and aligning them with the strengths of each service, you can make an informed decision that supports your business needs.
For complex, stateful workflows with long execution times and sophisticated recovery requirements, Amazon MWAA provides robust capabilities. For event-driven, serverless workflows with tight AWS integration and variable load patterns, AWS Step Functions is a strong fit.
Remember that these services are not mutually exclusive. Many organizations use both to address different workflow orchestration needs across their application portfolio. By focusing on your specific use case requirements, you can select the right tool for each job and build resilient, efficient workflow orchestration solutions on AWS.
If you have questions or feedback about choosing between these services, leave a comment.
Enterprises running transactional workloads on Amazon Aurora PostgreSQL-Compatible Edition (Aurora PostgreSQL) need their operational data available for analytics. However, analytical queries and cross-database joins compete for resources on OLTP-optimized clusters. Batch exports introduce latency, and when data spans multiple Aurora clusters, there’s no straightforward way to join datasets or run cross-domain analytics. Real-time change data capture (CDC) addresses this by streaming row-level changes into a separate analytics layer. However, most CDC approaches write append-only records that require downstream consumers to reconstruct current state from the change log.
In this post, we show you how to build a CDC pipeline that delivers query-ready Iceberg tables directly. The pipeline captures inserts, updates, and deletes from Aurora PostgreSQL and applies them as row-level operations in Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3). The destination tables always reflect the current state of the source database. You use Debezium on Amazon MSK Connect for change capture and Amazon Managed Streaming for Apache Kafka (Amazon MSK) for streaming. You also use AWS Lambda to transform CDC events and resolve operation semantics, and Amazon Data Firehose to deliver records into Iceberg tables. You deploy the infrastructure using the AWS Cloud Development Kit (AWS CDK).
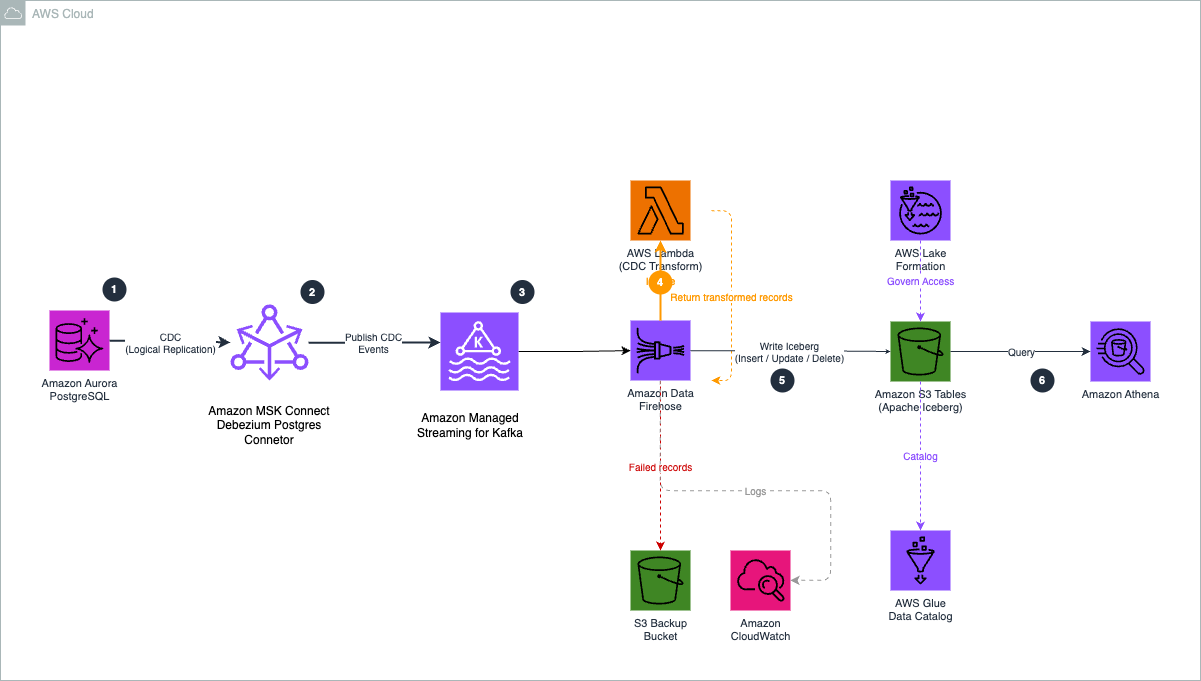
The following diagram shows the architecture of the CDC pipeline.
Figure 1. CDC pipeline architecture from Aurora PostgreSQL to Amazon S3 Tables.
The pipeline uses six components:
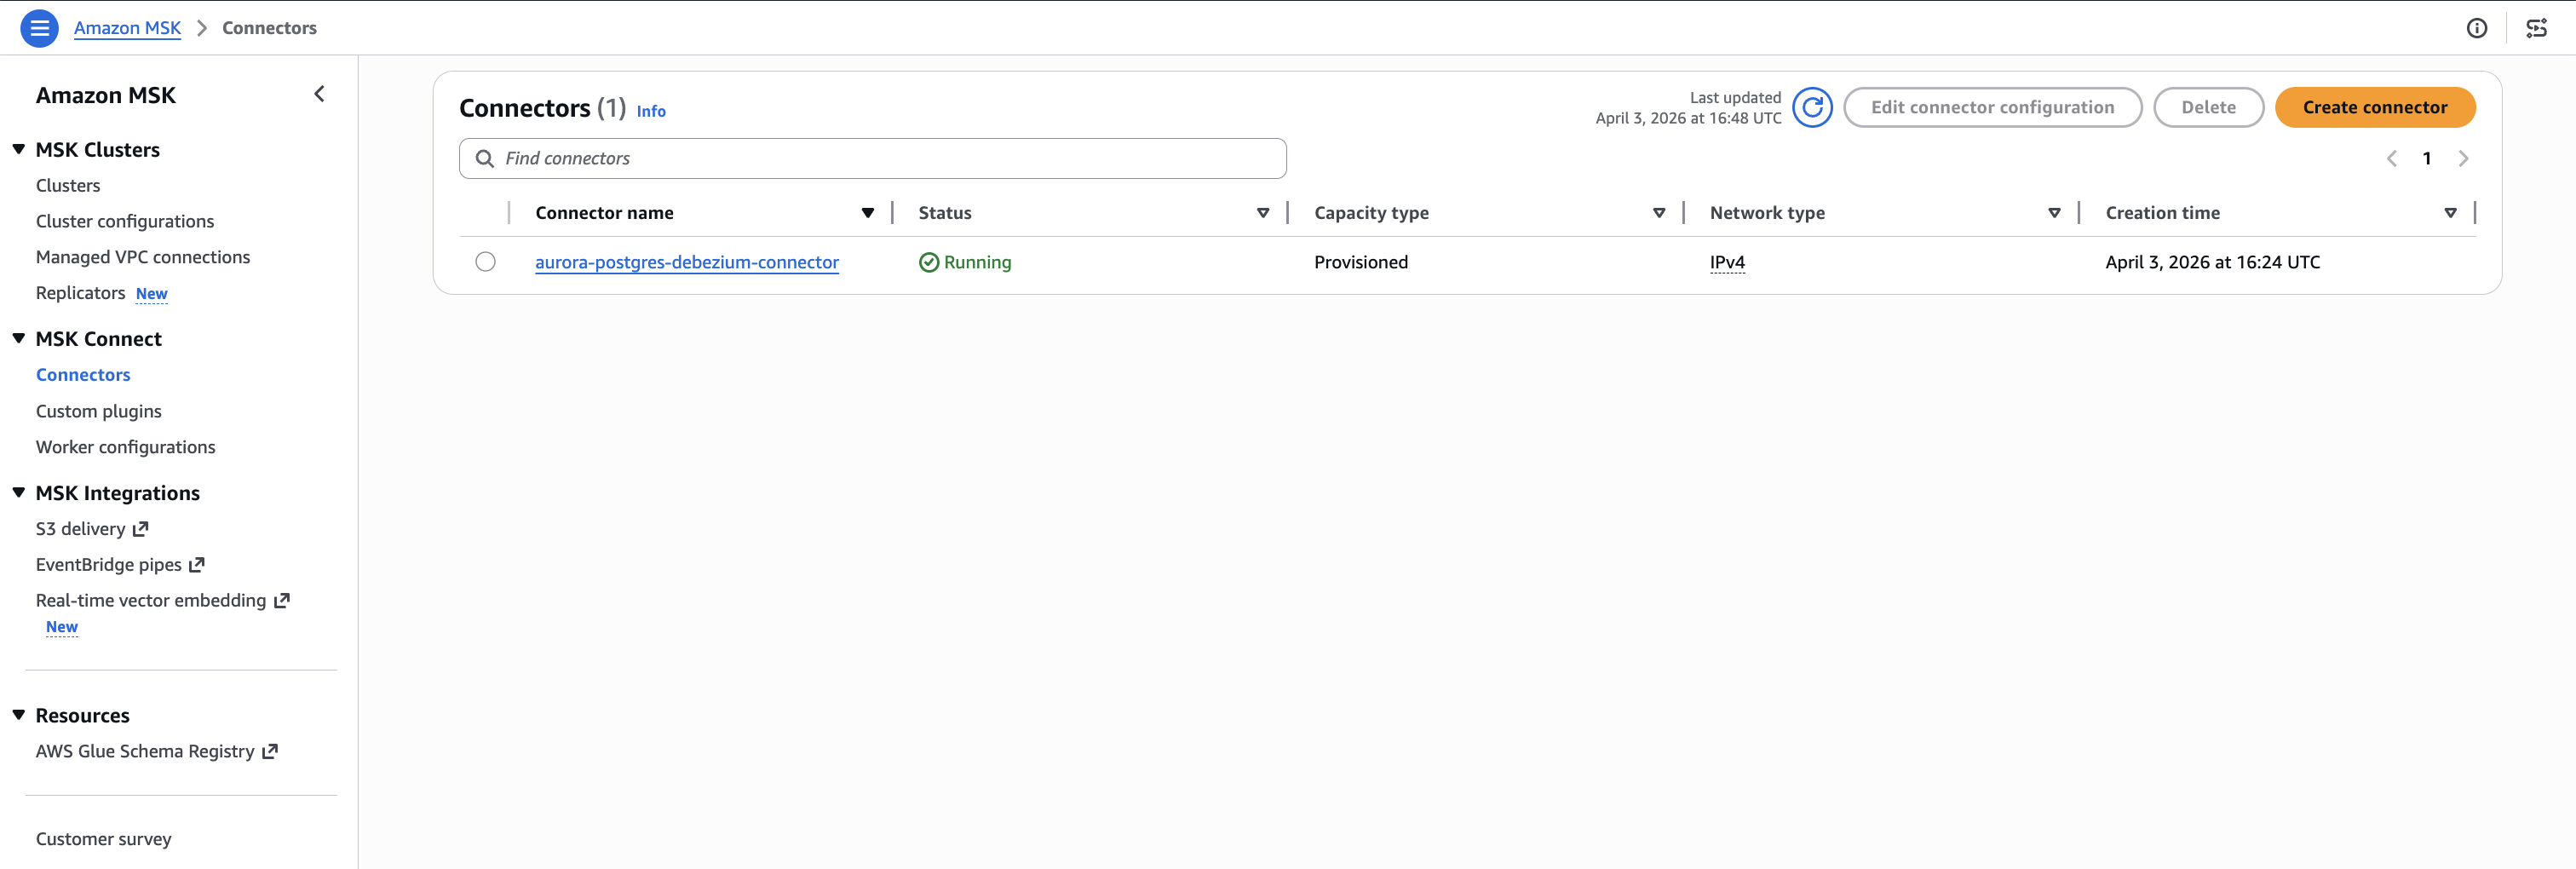
Aurora PostgreSQL to Debezium. Debezium runs on MSK Connect in your VPC and uses PostgreSQL’s native logical replication to stream row-level changes from the write-ahead log (WAL), with minimal impact on query performance.
Debezium to Amazon MSK. The ByLogicalTableRouterSMT reroutes CDC events from multiple tables into a single topic (aurora.cdc.all-tables), retaining the source table name in each message.
Amazon MSK to Firehose. Firehose connects to the MSK cluster using the IAM access control over AWS PrivateLink and continuously polls the topic for new messages.
Firehose to Lambda. For each batch, Firehose invokes the Lambda function to decode the Kafka message, flatten the Debezium envelope, and set otfMetadata routing with the destination table and operation type.
Firehose to S3 Tables. Firehose reads the otfMetadata, routes each record to the correct Iceberg table, and performs the appropriate row-level operation using configured unique keys (for example, order_id for orders). S3 Tables handles compaction and snapshot management automatically.
Firehose supports one MSK topic per delivery stream. The single-topic routing pattern uses a Debezium SMT to consolidate multiple tables into one topic, and a Lambda function to route records to the correct destination. With this, you can serve multiple tables through one Firehose stream, reducing cost and operational complexity.
Debezium event transformation
Debezium produces CDC events in an envelope structure containing both the previous and current state of a row, along with metadata about the source database, table, and operation type. However, Firehose expects records in a flattened JSON format with routing metadata that indicates the target table and operation type.
The Lambda function bridges this gap by performing three operations on each record:
Decode. When Firehose uses Amazon MSK as a source, it delivers the Kafka message value as a base64-encoded string in the kafkaRecordValue field. The function base64-decodes this field to obtain the raw Debezium JSON payload.
Flatten and extract. Pulls the row data from the Debezium envelope. For inserts and updates, the function uses the after field (the row after the change). For deletes, it uses the before field, because the after field is null when a row is removed.
Route. Sets the otfMetadata block with destinationTableName (extracted from the Debezium source.table field) and operation (mapped from Debezium’s single-character codes to Firehose’s operation types).
The following table shows how Debezium operation codes map to Firehose Iceberg operations:
Debezium code
Meaning
Firehose operation
c
Row created (insert)
insert
u
Row updated
update
d
Row deleted
delete
r
Snapshot read (initial load)
insert
When Debezium starts with snapshot.mode=initial, it reads all existing rows and emits them as r (read) events. These represent rows that existed before CDC began, so they are mapped to insert to establish the baseline state in the destination tables.
For example, the function transforms this Debezium envelope:
The kafkaRecordValue contains the base64-encoded flattened row data (for example, {"order_id": 1, "customer_id": 1, "total_amount": 299.99}), and the otfMetadata block tells Firehose which table to write to and which operation to perform.
PostgreSQL supports change data capture through its logical replication framework, which allows database changes to be streamed from the write-ahead log (WAL). Debezium uses this mechanism to continuously read row-level changes and publish them to Kafka topics.
Create a publication that defines which tables are included in the change stream. Debezium automatically creates the logical replication slot when the connector starts for the first time, so you don’t need to create one manually.
CREATE PUBLICATION dbz_publication FOR TABLE public.orders, public.products;
Verify the publication was created:
SELECT * FROM pg_publication WHERE pubname = 'dbz_publication';
You should see one row returned, confirming the publication is active.
Important: When the Debezium connector starts (Step 6), it creates a replication slot named debezium_slot. This slot retains WAL segments until consumed. If the connector is stopped for an extended period, WAL segments can accumulate and increase storage usage on the Aurora cluster. Monitor the ReplicationSlotDiskUsageAmazon CloudWatch metric for your Aurora cluster.
Step 2: Build and register the Debezium plugin
MSK Connect runs connectors using custom plugins that you upload to Amazon S3. In this step, you download the Debezium PostgreSQL connector, package it as a ZIP file, upload it to S3, and register it with MSK Connect.
First, create an S3 bucket for the plugin, or use an existing metadata management bucket:
Note the customPluginArn and workerConfigurationArn from the output. You need these for the CDK configuration in the next step.
Note: The custom plugin and worker configuration are created through the AWS CLI because the Debezium connector JARs must be downloaded from the Debezium project and packaged manually. The remaining infrastructure is deployed using the AWS CDK in the following steps.
Step 3: Configure the CDK project
Clone the sample repository and install dependencies:
git clone https://github.com/aws-samples/sample-aurora-cdc-s3tables.git
cd sample-aurora-cdc-s3tables/cdk
npm install
Open cdk/lib/v2/config.ts and update the configuration values to match your environment:
export const CONFIG = {
account: '<your-account-id>',
region: '<your-region>',
// VPC - must match your Aurora cluster's VPC
vpcId: '<your-vpc-id>',
subnetIds: ['<subnet-1>', '<subnet-2>'],
auroraSecurityGroupId: '<aurora-security-group-id>',
// Aurora connection details
auroraEndpoint: '<aurora-cluster-endpoint>',
auroraPort: '5432',
auroraDbName: '<database-name>',
auroraUser: '<db-user>',
auroraSecretArn: '<secrets-manager-arn>',
// Debezium - use the ARNs from Step 2
debeziumPluginArn: '<customPluginArn-from-step-2>',
debeziumWorkerConfigArn: '<workerConfigurationArn-from-step-2>',
debeziumPluginBucket: '<your-plugin-bucket-name>',
debeziumTopicPrefix: 'aurora.cdc',
debeziumTables: 'public.orders,public.products',
// S3 Tables - the table bucket name must be globally unique
s3TablesBucketName: '<your-table-bucket-name>',
s3TablesNamespace: 'aurora_cdc',
tables: ['orders', 'products'],
tableKeys: { orders: 'order_id', products: 'product_id' },
// Firehose - general purpose S3 bucket for failed record backup
firehoseBackupBucket: '<your-backup-bucket-name>',
};
Key configuration notes:
auroraSecurityGroupId. The security group attached to your Aurora cluster. The CDK creates an MSK security group with ingress rules allowing traffic from this security group, and a reverse rule allowing MSK Connect workers to reach Aurora on port 5432.
tableKeys. The primary key column for each table. Firehose uses these to match incoming records against existing rows for update and delete operations in the Iceberg tables.
Amazon MSK cluster (2x kafka.m5.large brokers) with dual authentication (IAM for Firehose, unauthenticated for Debezium), custom configuration with auto.create.topics.enable=true, security groups with ingress rules for Aurora and MSK Connect workers
CdcMskConnectIam
MSK Connect service execution role with permissions for Kafka cluster operations, VPC networking, S3 plugin access, and AWS Secrets Manager; Amazon CloudWatch Logs group for connector logs
CdcS3Tables
S3 table bucket, aurora_cdc namespace, two Iceberg tables (orders, products) with column schemas
CdcLambdaTransform
Lambda function for CDC event transformation and multi-table routing
Firehose delivery stream with MSK as source (private connectivity through AWS PrivateLink), Lambda processing, Apache Iceberg Tables as destination with two table configurations, and S3 backup bucket for failed records
The MSK cluster takes approximately 25 minutes to create. The Debezium connector takes approximately 5 minutes after the cluster is ready. You can monitor the deployment progress in the AWS CloudFormation console.
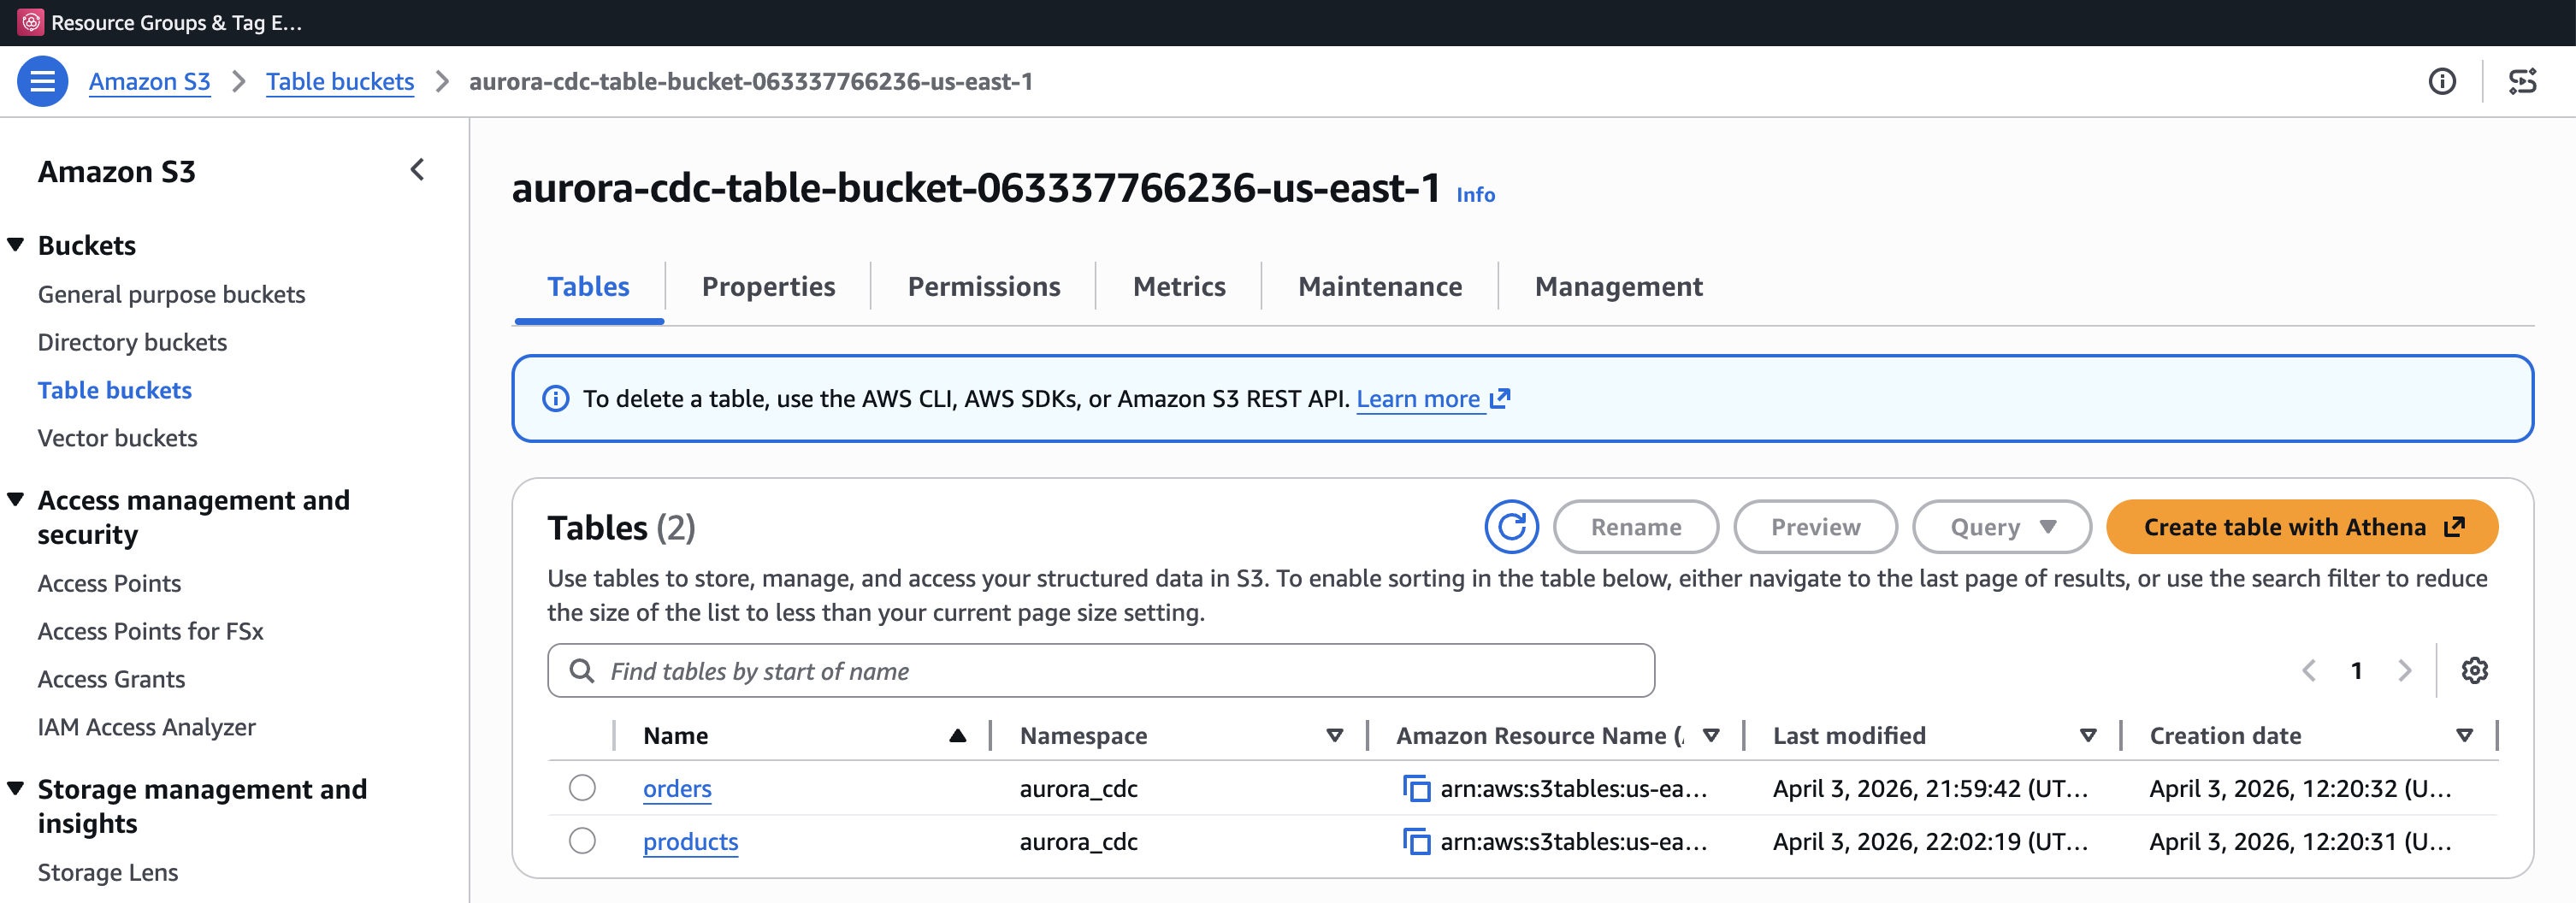
After the deployment completes, you can verify the resources in the AWS console. The S3 table bucket shows the two Iceberg tables in the aurora_cdc namespace.
Figure 2. S3 table bucket showing the orders and products Iceberg tables in the aurora_cdc namespace.
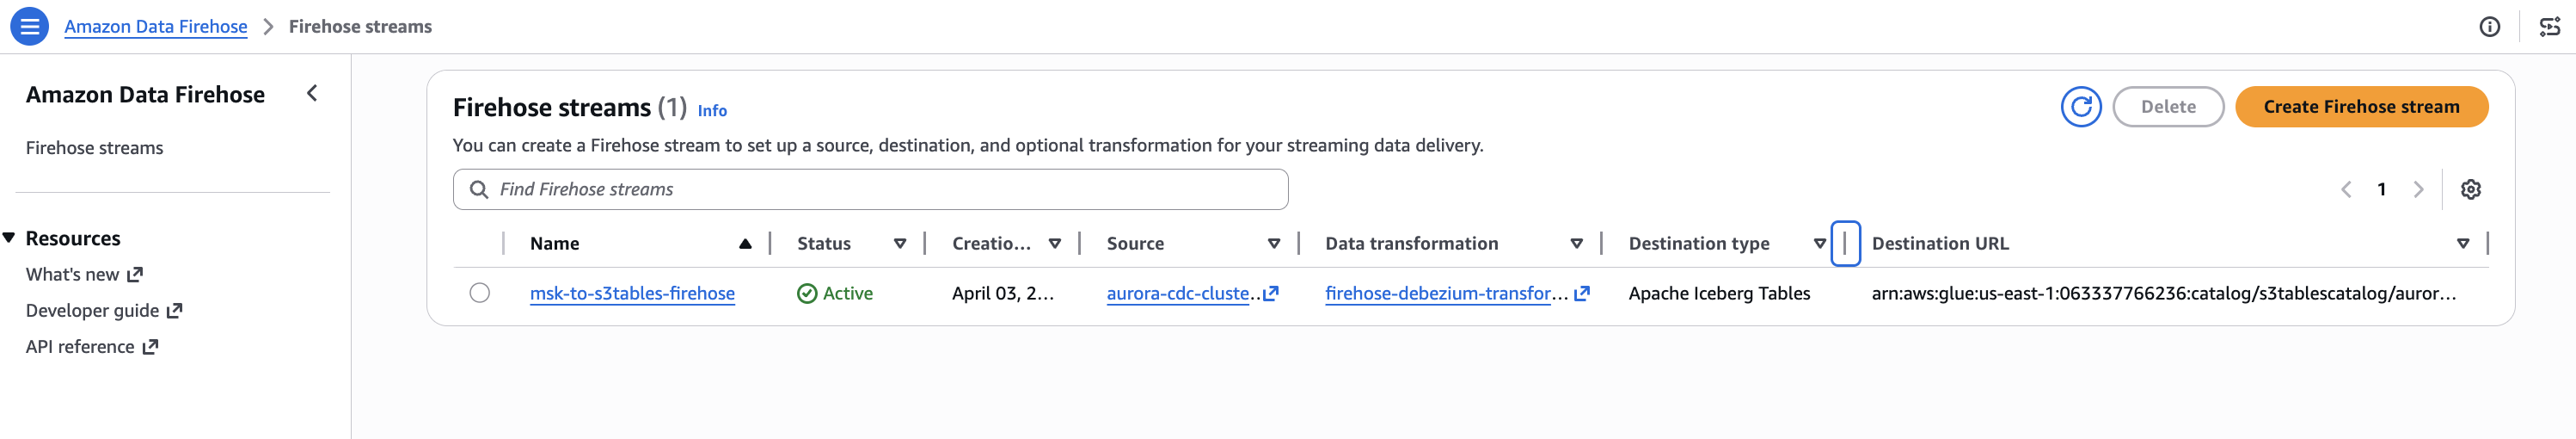
The Firehose delivery stream shows the MSK source, Lambda transformation, and Apache Iceberg Tables destination.
Figure 3. Amazon Data Firehose delivery stream with MSK source, Lambda transformation, and Apache Iceberg Tables destination.
The MSK cluster uses dual authentication (IAM for Firehose, unauthenticated for Debezium through TLS_PLAINTEXT), multi-VPC private connectivity for Firehose PrivateLink access, and auto.create.topics.enable=true so Debezium can create topics on first connect. VPC connectivity and the cluster resource policy are configured as CLI steps in Step 5.
Step 5: Enable MSK VPC connectivity, grant Lake Formation permissions, and apply MSK cluster policy
After the CDK deployment completes, enable multi-VPC private connectivity with IAM on the MSK cluster. Firehose requires this to create an AWS PrivateLink endpoint to the MSK brokers. This setting can’t be configured during cluster creation and must be applied as an update, which triggers a rolling broker restart (approximately 20–30 minutes).
# Get the cluster ARN and current version from the CdcMskCluster stack outputs
MSK_ARN=<msk-cluster-arn>
CLUSTER_VERSION=$(aws kafka describe-cluster-v2 \
    --cluster-arn $MSK_ARN \
    --region <your-region> \
    --query 'ClusterInfo.CurrentVersion' --output text)
# Enable VPC connectivity with IAM
aws kafka update-connectivity \
    --cluster-arn $MSK_ARN \
    --current-version $CLUSTER_VERSION \
    --connectivity-info '{"VpcConnectivity":{"ClientAuthentication":{"Sasl":{"Iam":{"Enabled":true}}}}}' \
    --region <your-region>
Wait for the cluster state to return to ACTIVE before proceeding:
Next, grant the Firehose IAM role permissions through AWS Lake Formation. S3 Tables uses a sub-catalog format for the CatalogId parameter, which differs from the standard AWS Glue Data Catalog. These permissions require a data lake administrator identity.
Grant database-level and table-level permissions to the Firehose role:
# Grant database-level permissions
aws lakeformation grant-permissions \
    --region <your-region> \
    --principal '{"DataLakePrincipalIdentifier": "<firehose-role-arn>"}' \
    --resource '{"Database": {"CatalogId": "<account-id>:s3tablescatalog/<table-bucket-name>", "Name": "aurora_cdc"}}' \
    --permissions '["ALL"]'
# Grant table-level permissions (wildcard for the tables in the namespace)
aws lakeformation grant-permissions \
    --region <your-region> \
    --principal '{"DataLakePrincipalIdentifier": "<firehose-role-arn>"}' \
    --resource '{"Table": {"CatalogId": "<account-id>:s3tablescatalog/<table-bucket-name>", "DatabaseName": "aurora_cdc", "TableWildcard": {}}}' \
    --permissions '["ALL"]'
Note the CatalogId format: <account-id>:s3tablescatalog/<table-bucket-name>. This is specific to S3 Tables and tells Lake Formation to look up permissions in the S3 Tables catalog rather than the default Glue Data Catalog. For more information, see Integrating Amazon S3 Tables with AWS analytics services.
Next, attach a resource-based policy to the MSK cluster that grants the Firehose service principal permission to create VPC connections:
You can find the <msk-cluster-arn> in the CdcMskCluster stack outputs from Step 4, and the <firehose-role-arn> in the CdcFirehoseRole stack outputs.
Step 6: Create the Debezium connector
With the MSK cluster running and Lake Formation permissions in place, create the Debezium connector using the MSK Connect API. The connector reads changes from Aurora PostgreSQL and publishes them to the MSK topic.
Firehose supports only one MSK topic per delivery stream, so each source table would otherwise need its own Firehose stream and VPC connection. To avoid this, the connector uses the Debezium ByLogicalTableRouter Single Message Transform (SMT) to route changes from multiple tables into a single topic (aurora.cdc.all-tables). The Lambda function then uses the source table name in each message to direct records to the correct Iceberg table. This single-topic pattern uses one Firehose stream for multiple tables, reducing cost and operational complexity.
First, retrieve the MSK bootstrap servers from the cluster:
The <msk-security-group-id> and <msk-connect-service-role-arn> can be found in the CdcMskCluster and CdcMskConnectIam stack outputs respectively. The ByLogicalTableRouterSingle Message Transform routes CDC events from the monitored tables into a single topic (aurora.cdc.all-tables).
Step 7: Verify the Debezium connector
After creating the connector, verify that it is running and has completed its initial snapshot.
You should see messages indicating the transition to streaming mode:
Finished exporting 0 records for table 'public.orders' (1 of 2 tables)
Finished exporting 0 records for table 'public.products' (2 of 2 tables)
Snapshot completed
Starting streaming
If the tables were empty when the connector started, the export count is 0. If you had existing data, the snapshot captures the existing rows as r (read) operations, which the Lambda function maps to insert operations in the Iceberg tables.
Verify that the Firehose delivery stream is active:
Insert test data into the Aurora PostgreSQL source tables. Each insert triggers a CDC event that flows through the pipeline: Aurora WAL to Debezium to MSK topic to Firehose to Lambda transform to S3 Tables.
This creates six records across two tables. Each record generates a Debezium CDC event with operation type c (create), which the Lambda function maps to an insert operation in the corresponding Iceberg table.
Step 9: Verify data delivery
Check the Firehose IncomingRecords metric to confirm records are flowing through the delivery stream:
You should see a Sum value of 6 or more. If the value is 0, wait another minute and retry. There can be a short delay between MSK topic delivery and Firehose metric reporting.
If records aren’t appearing, check the Firehose error output in the backup S3 bucket and the Lambda function’s CloudWatch Logs for transformation errors.
Step 10: Query data using Amazon Athena
With data delivered to S3 Tables, you can query the Iceberg tables using Amazon Athena. S3 Tables integrates with the AWS Glue Data Catalog as a sub-catalog, so you reference tables using the S3 Tables catalog format.
Tip: If records aren’t appearing in Athena, check the Firehose IncomingRecords CloudWatch metric and the Lambda function’s CloudWatch Logs for transformation errors.
Open the Athena console, select the AwsDataCatalog data source, and run the following queries:
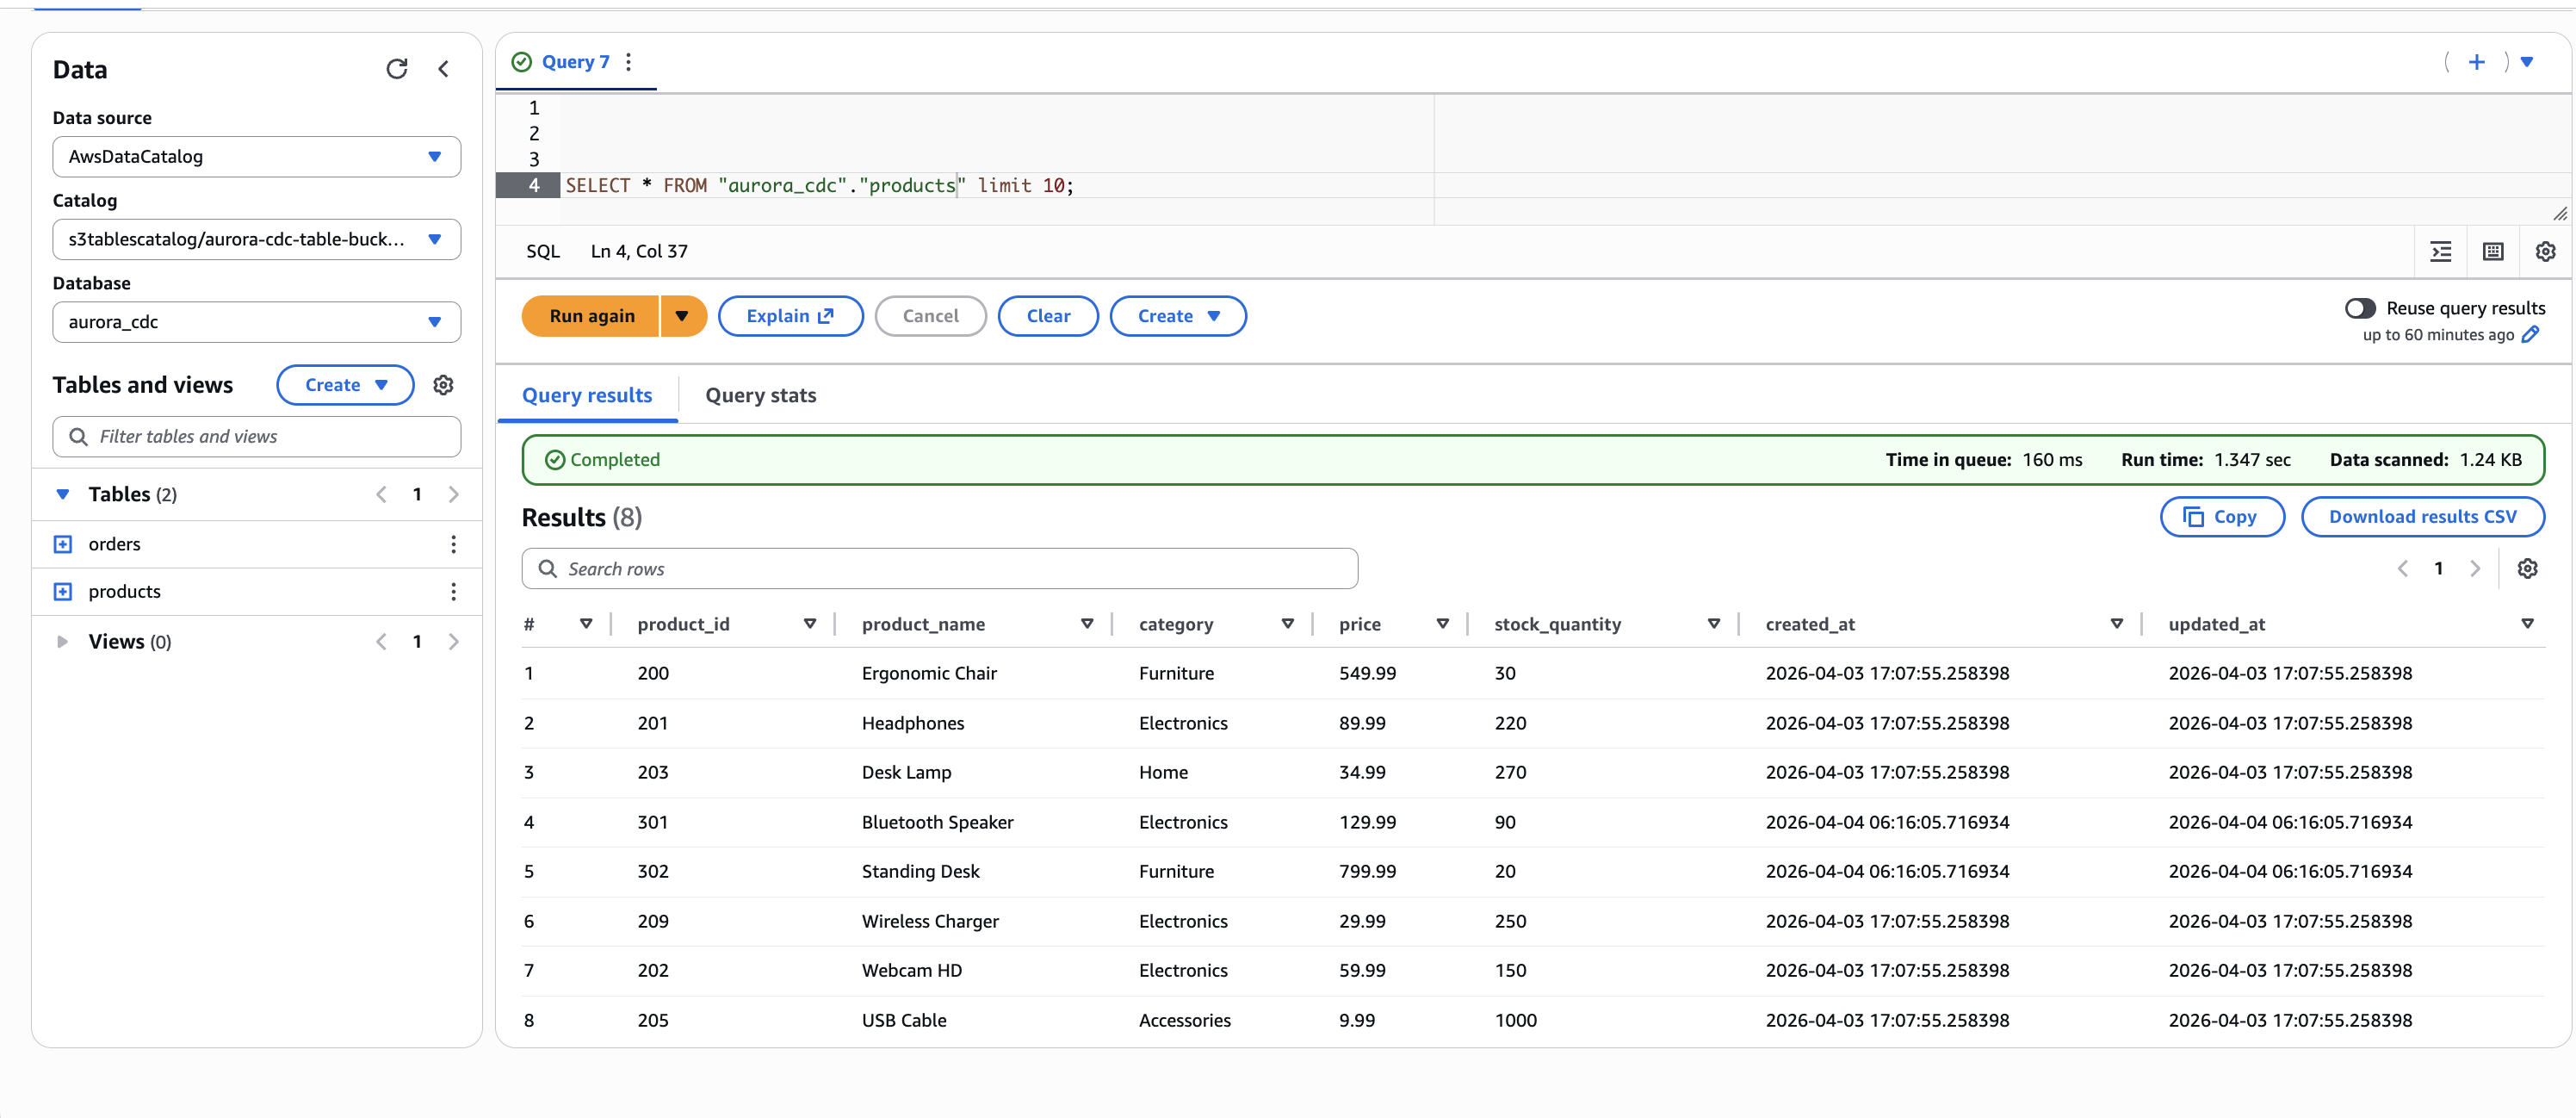
SELECT * FROM "s3tablescatalog/<table-bucket-name>"."aurora_cdc"."products" LIMIT 10;
SELECT * FROM "s3tablescatalog/<table-bucket-name>"."aurora_cdc"."orders" LIMIT 10;
Replace <table-bucket-name> with your S3 table bucket name. You should see the records from the initial snapshot that Debezium captured when the connector started.
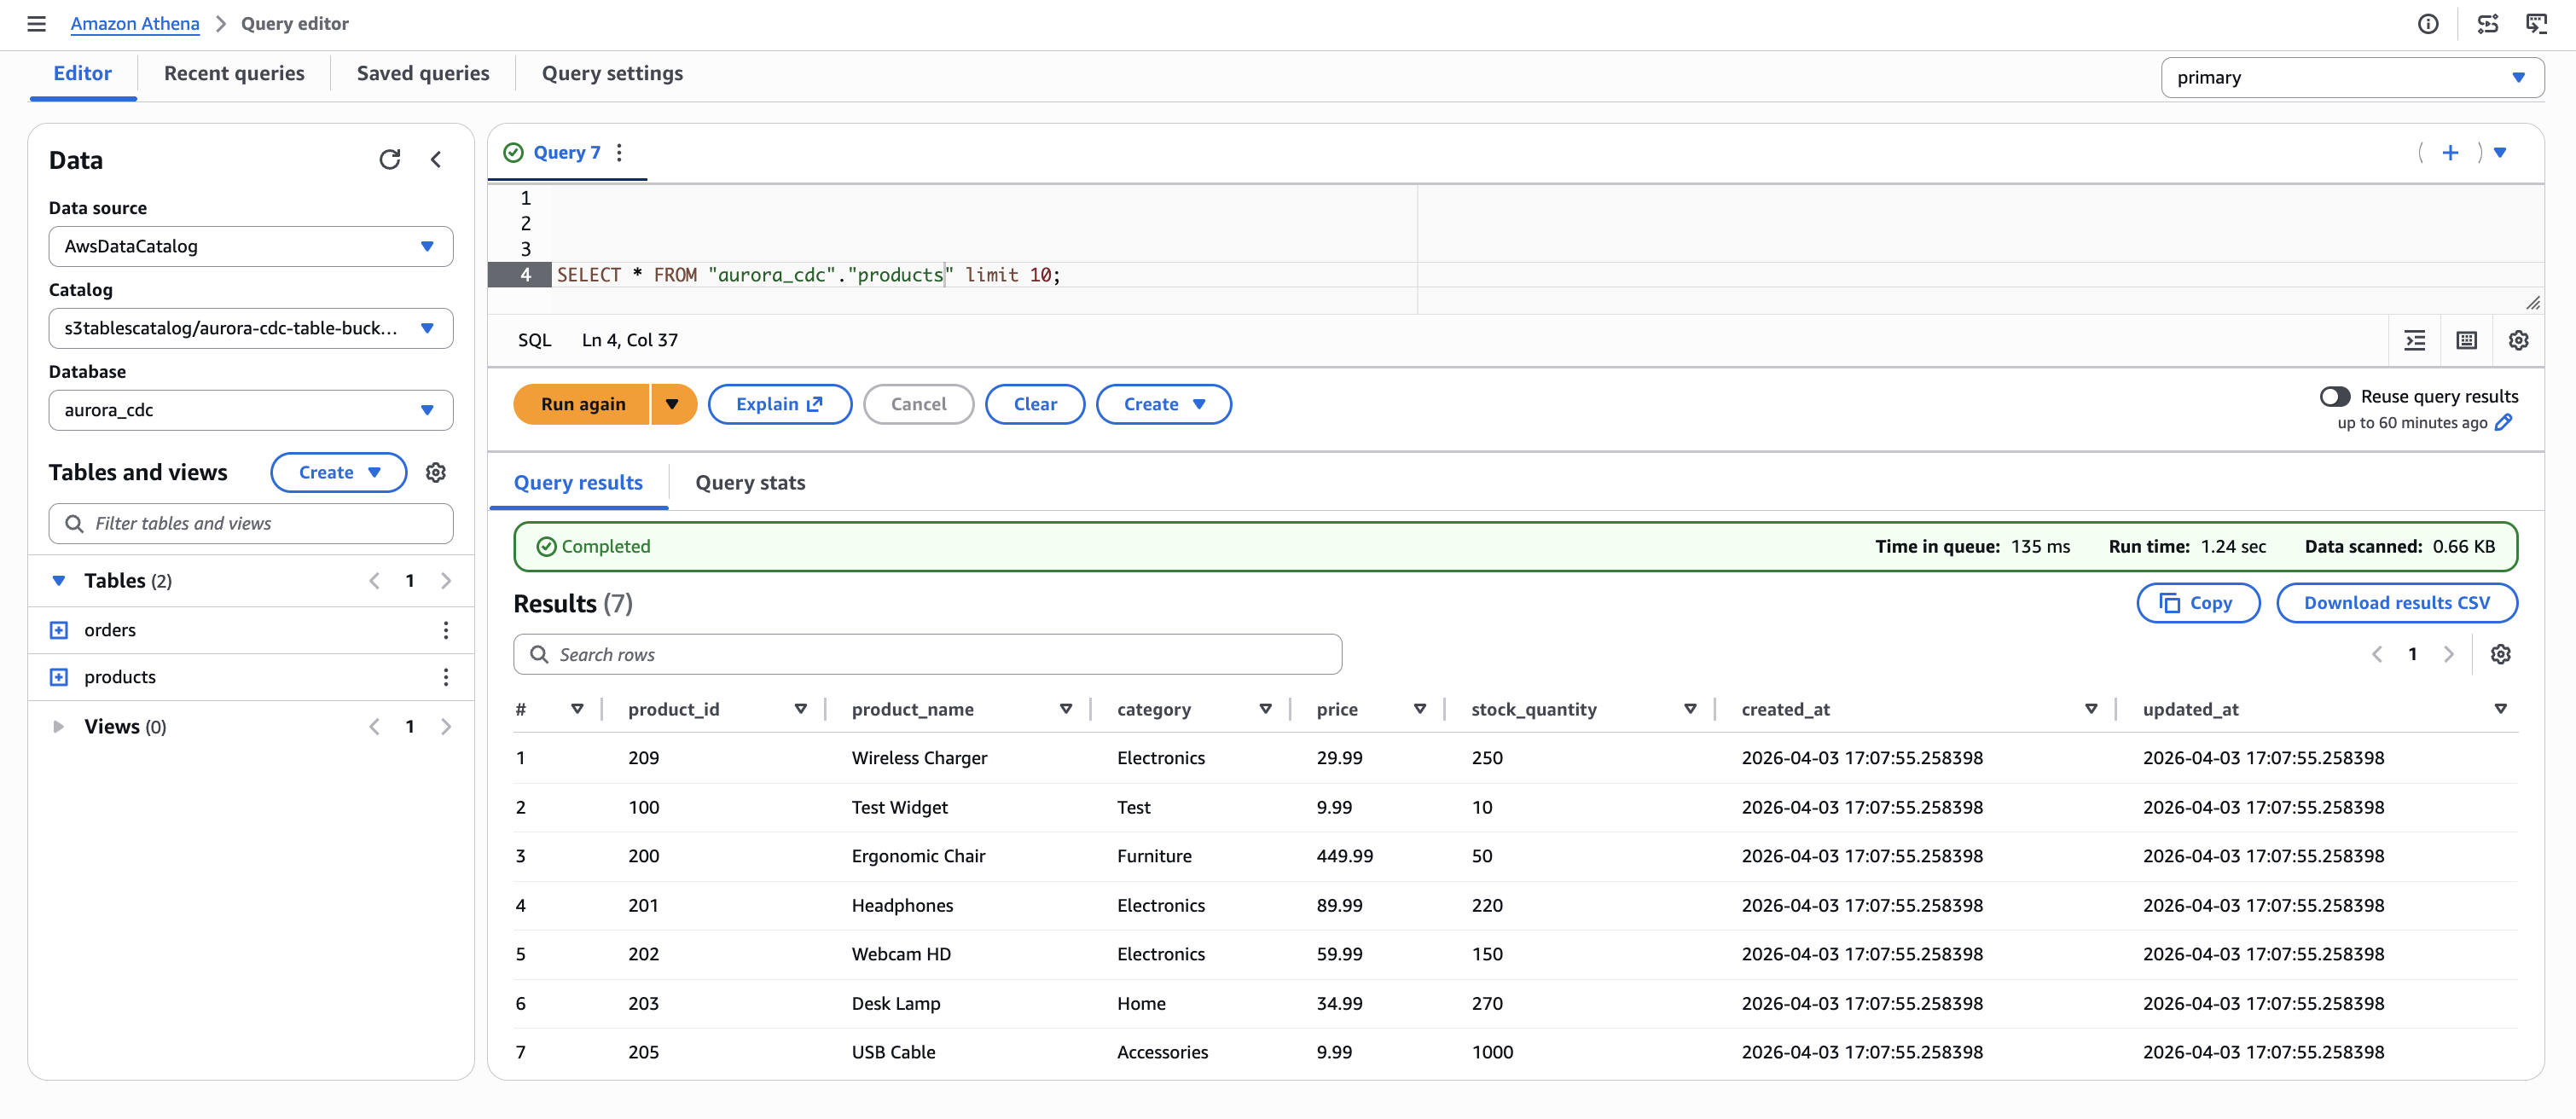
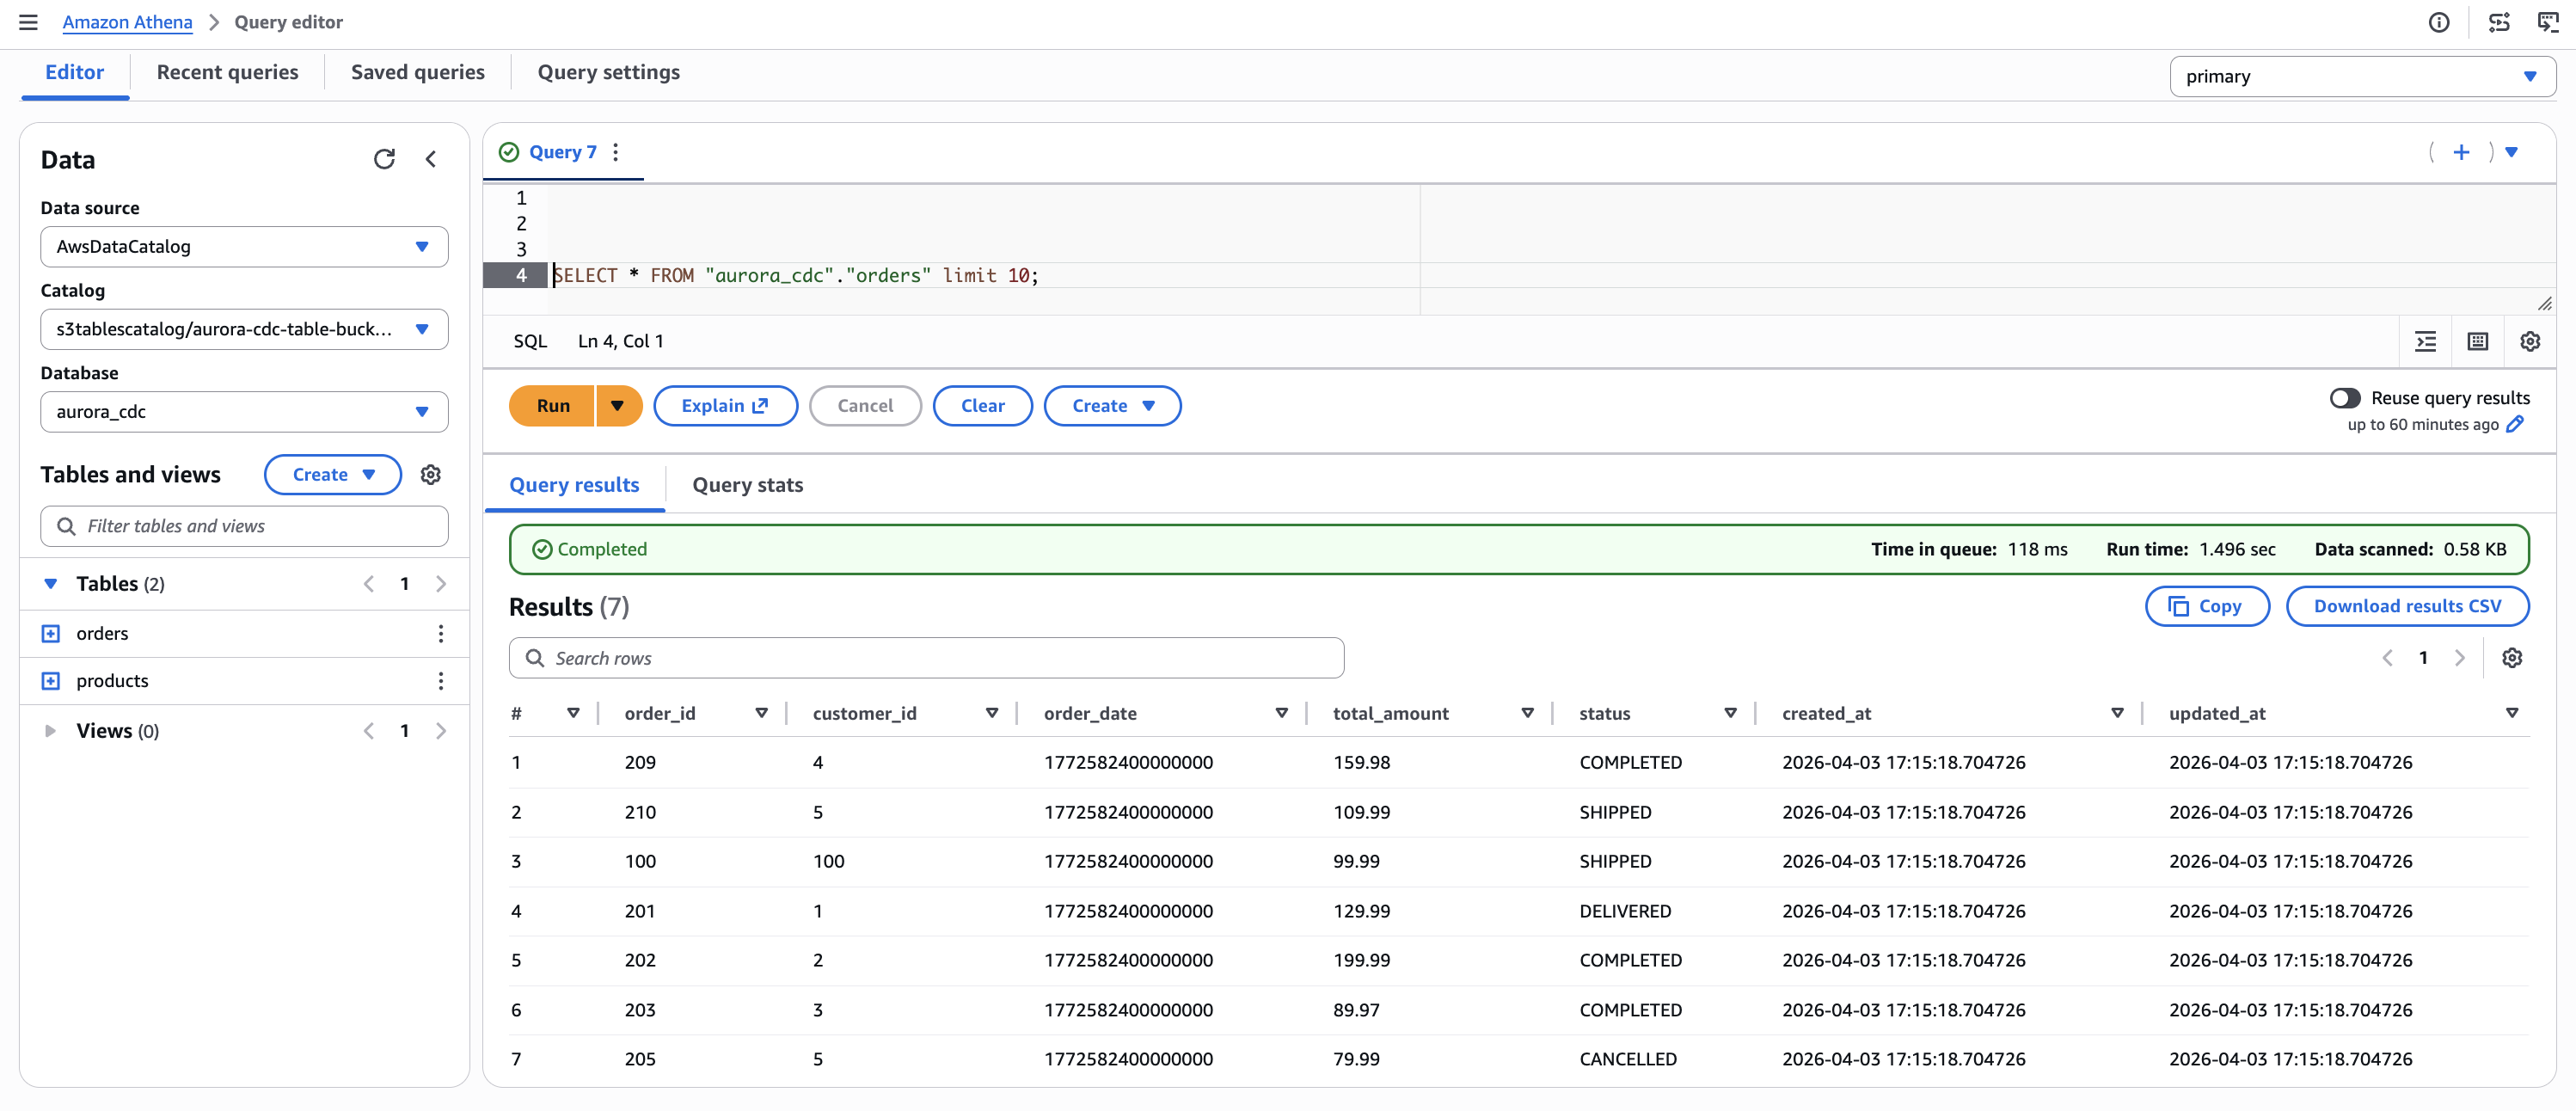
The following figures show the initial state of both tables as queried through Athena. At this point, the products table contains seven records and the orders table contains seven records, captured during the Debezium initial snapshot.
Figure 5. Initial state of the products table in Amazon Athena, showing seven records captured from Aurora PostgreSQL through the CDC pipeline.
Figure 6. Initial state of the orders table in Amazon Athena, showing seven records captured from Aurora PostgreSQL through the CDC pipeline.
Now test that update and delete operations propagate correctly. Run the following statements in Aurora:
-- Insert new records
INSERT INTO public.products (product_name, category, price, stock_quantity)
VALUES ('Bluetooth Speaker', 'Electronics', 129.99, 90), ('Standing Desk', 'Furniture', 799.99, 20);
INSERT INTO public.orders (customer_id, order_date, total_amount, status)
VALUES (201, '2026-04-03', 149.99, 'NEW'), (202, '2026-04-03', 249.50, 'NEW'), (203, '2026-04-03', 79.90, 'NEW');
-- Update existing records
UPDATE public.products SET stock_quantity = 30, price = 549.99 WHERE product_name = 'Ergonomic Chair';
UPDATE public.orders SET status = 'DELIVERED' WHERE order_id = 201;
-- Delete a record
DELETE FROM public.products WHERE product_name = 'Test Widget';
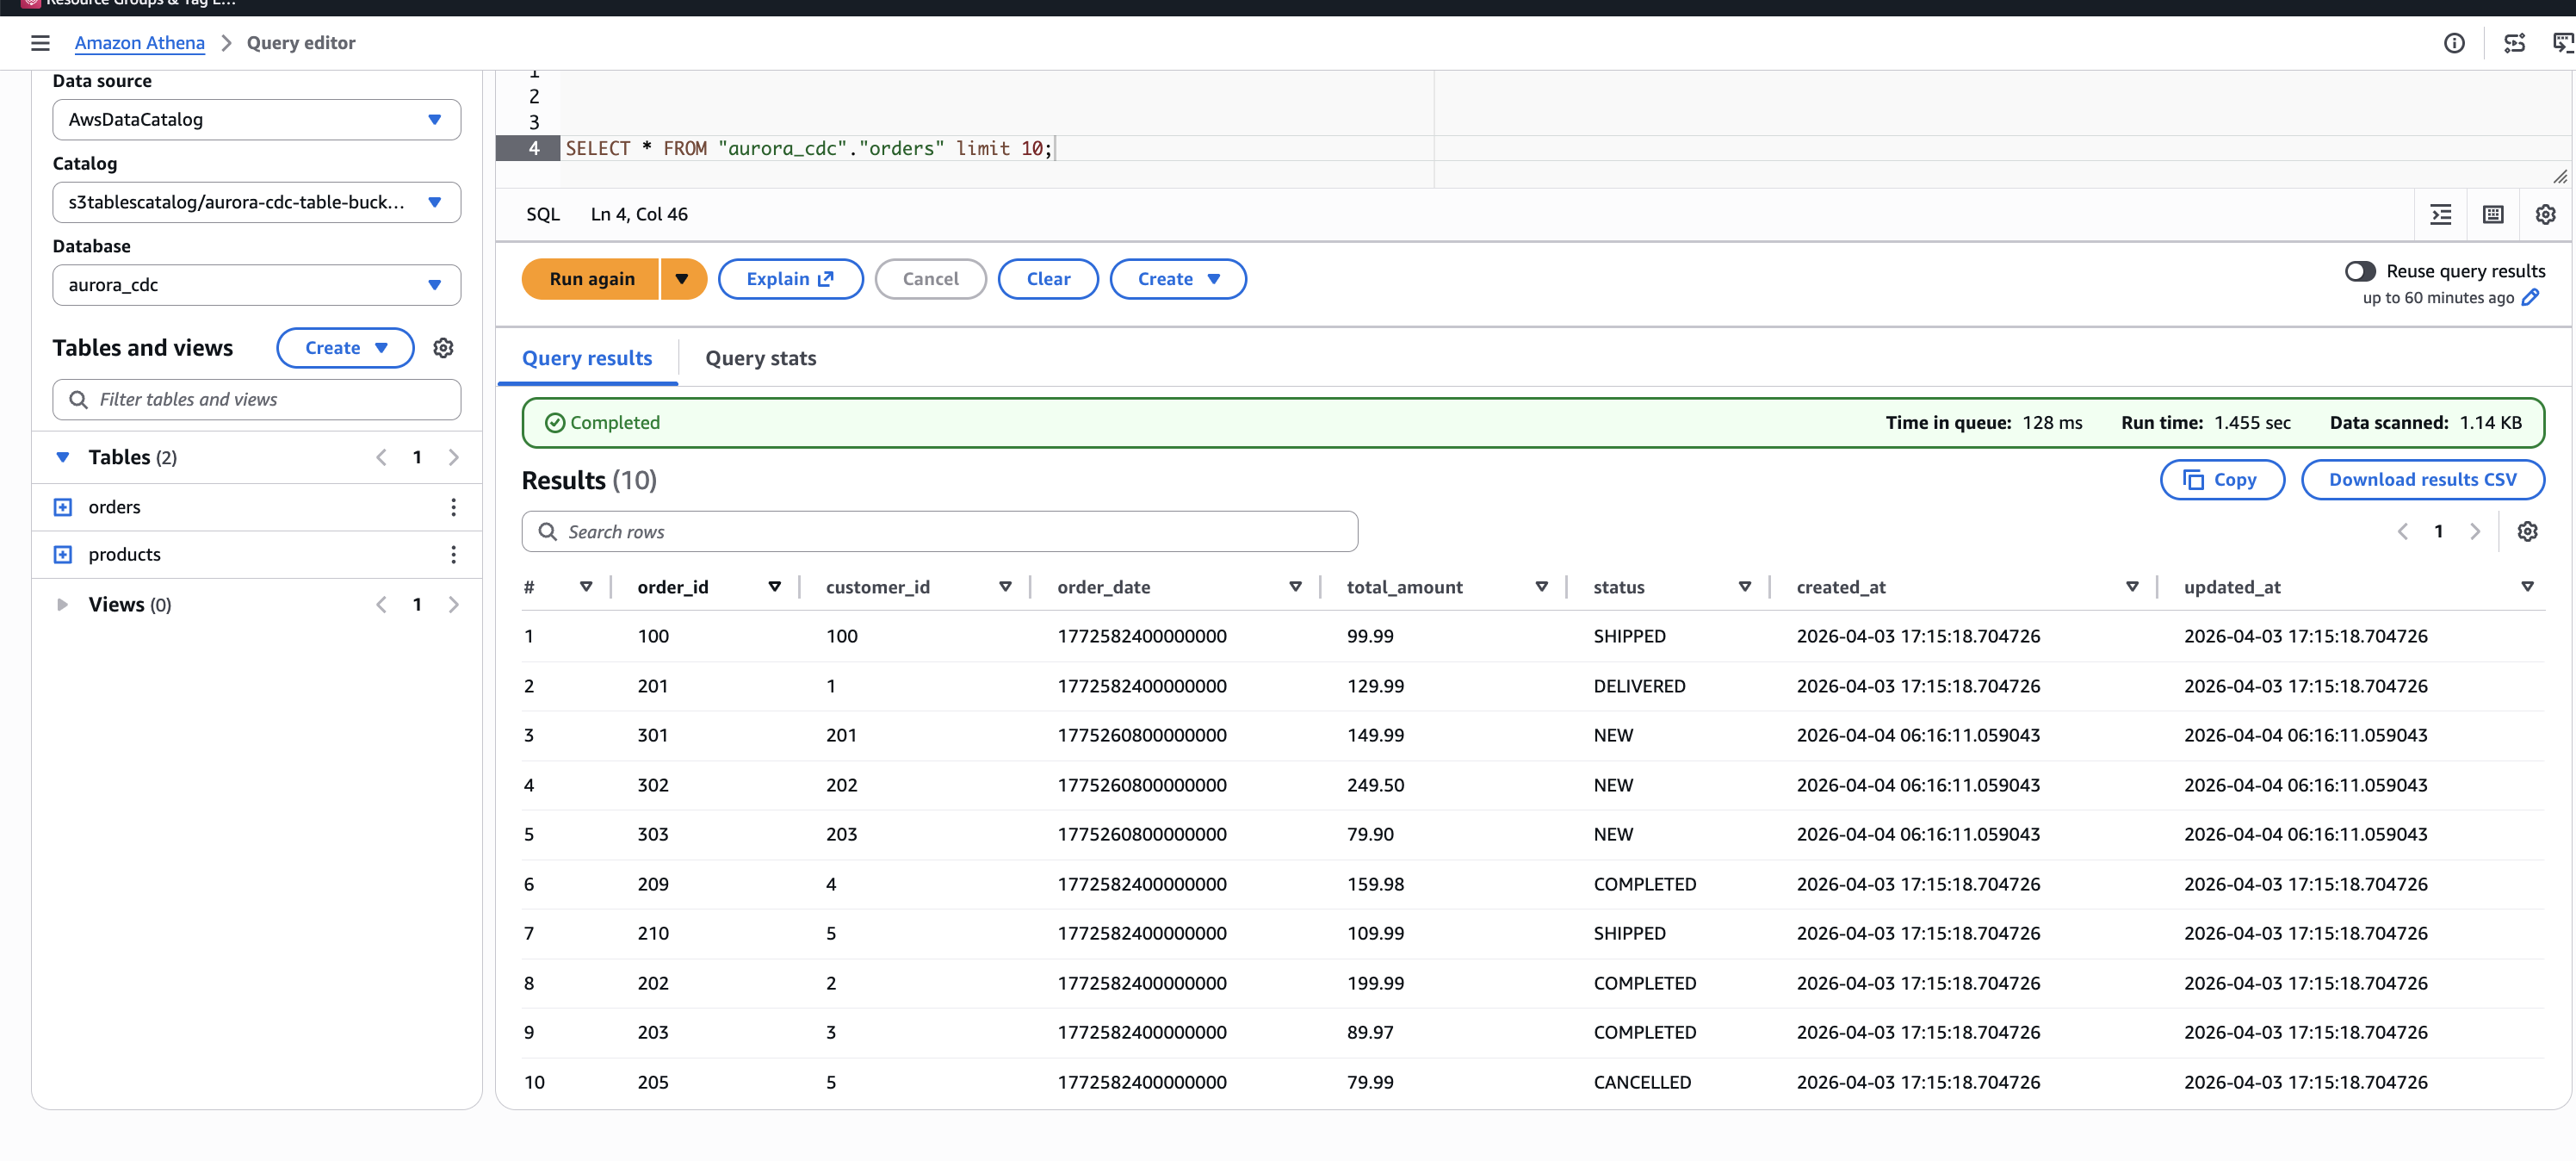
Wait for the changes to propagate through the pipeline, then query Athena again. The following figures show the results after the insert, update, and delete operations have been applied.
In the products table, the Test Widget record (product_id 100) is no longer present because it was removed by the delete operation. The Ergonomic Chair row now reflects the updated price (549.99) and stock quantity (30). Two new records, Bluetooth Speaker and Standing Desk, appear with a later created_at timestamp, confirming they were inserted after the initial snapshot.
Figure 7. Products table after CDC operations. The Ergonomic Chair, Headphones, and Desk Lamp rows reflect updated values. Bluetooth Speaker and Standing Desk are newly inserted records. The Test Widget record has been removed by the delete operation.
In the orders table, order 100 now shows a status of SHIPPED and order 201 shows DELIVERED, reflecting the update operations. Three new orders (301, 302, 303) appear with status NEW and a later timestamp, confirming they were inserted after the initial load.
Figure 8. Orders table after CDC operations. Orders 100 and 201 reflect updated status values. Orders 301, 302, and 303 are newly inserted records.
This confirms that the pipeline correctly handles the three CDC operation types: inserts, updates, and deletes are captured from the Aurora WAL by Debezium, routed through the single MSK topic, transformed by the Lambda function, and applied as row-level Iceberg operations by Firehose.
S3 Tables handles compaction and snapshot management for Iceberg tables automatically, including compaction of small data files and expiration of old snapshots. You don’t need to run manual maintenance operations.
You can also use Iceberg’s time travel capability to query the table as it existed before the updates:
SELECT * FROM "s3tablescatalog/<table-bucket-name>"."aurora_cdc"."orders"
FOR TIMESTAMP AS OF current_timestamp - interval '5' minute;
This returns the original data before the update, demonstrating the time travel capability that Apache Iceberg provides through S3 Tables.
Cleaning up
To avoid ongoing charges, delete the resources in reverse dependency order.
Delete the CDK stacks:
cd cdk
npx cdk --app "npx ts-node bin/app-v2.ts" destroy --all
Delete the Debezium custom plugin and worker configuration that were created through the AWS CLI in Step 2:
Clean up the Aurora PostgreSQL replication resources:
SELECT pg_drop_replication_slot('debezium_slot');
DROP PUBLICATION dbz_publication;
Important: The replication slot (debezium_slot) was created automatically by Debezium. If you plan to redeploy the pipeline later, you don’t need to drop the slot and publication. However, the replication slot continues to retain WAL segments while the connector isn’t running, which can increase storage usage on the Aurora cluster. The MSK cluster is the largest cost component of this solution and can’t be paused. It can only be deleted and recreated.
Conclusion
In this post, we showed you how to build a near real-time CDC pipeline from Aurora PostgreSQL to Apache Iceberg tables in Amazon S3 Tables. The key architectural decisions include:
Single-topic routing with multi-table delivery. The Debezium ByLogicalTableRouter SMT routes CDC events from multiple tables through one MSK topic, and the Lambda otfMetadata routing directs each record to the correct Iceberg table. This reduces VPC connection costs by using a single Firehose stream for inserts, updates, and deletes across multiple destination tables.
Fully managed CDC pipeline. MSK Connect runs Debezium, Firehose handles delivery with automatic retries, and S3 Tables manages Iceberg compaction and snapshots. The Lambda transform preserves CDC semantics by mapping Debezium operations to Iceberg row-level operations.
Governed lakehouse access. Lake Formation controls fine-grained access to the Iceberg tables, and data from multiple isolated Aurora clusters can be unified in a single S3 Tables namespace for cross-domain analytics.
Infrastructure as code. Six AWS CDK stacks deploy the core pipeline, with Lake Formation permissions, MSK cluster policy, and Debezium connector configured through documented CLI steps.
Upgrading Apache Spark applications across major versions means tracking down breaking changes, manually debugging failures from log files, and running repeated test cycles. This process can stretch across weeks for complex code bases.
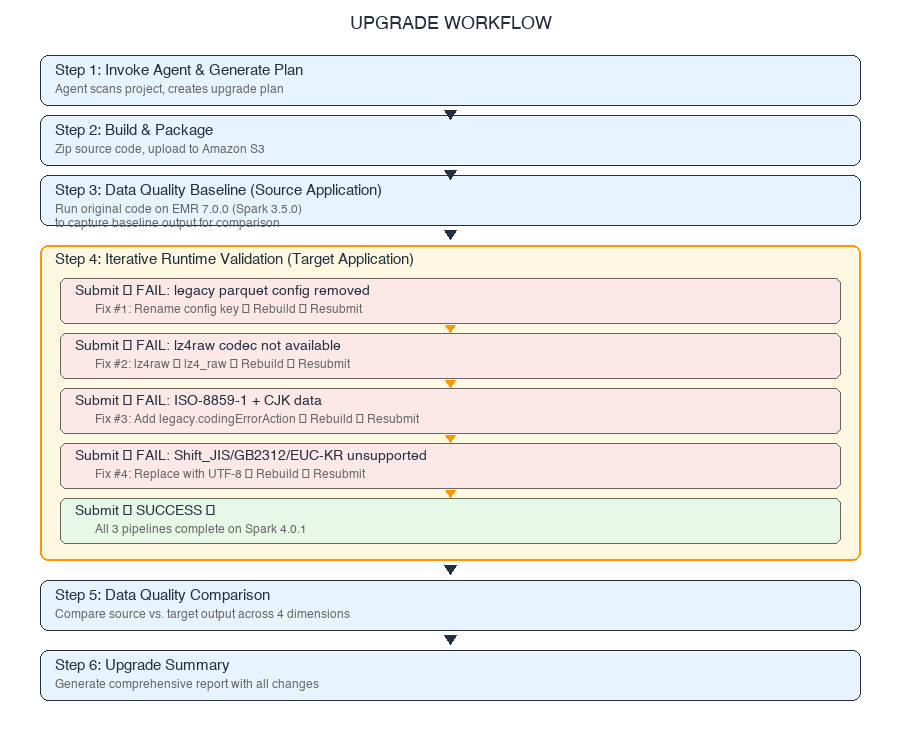
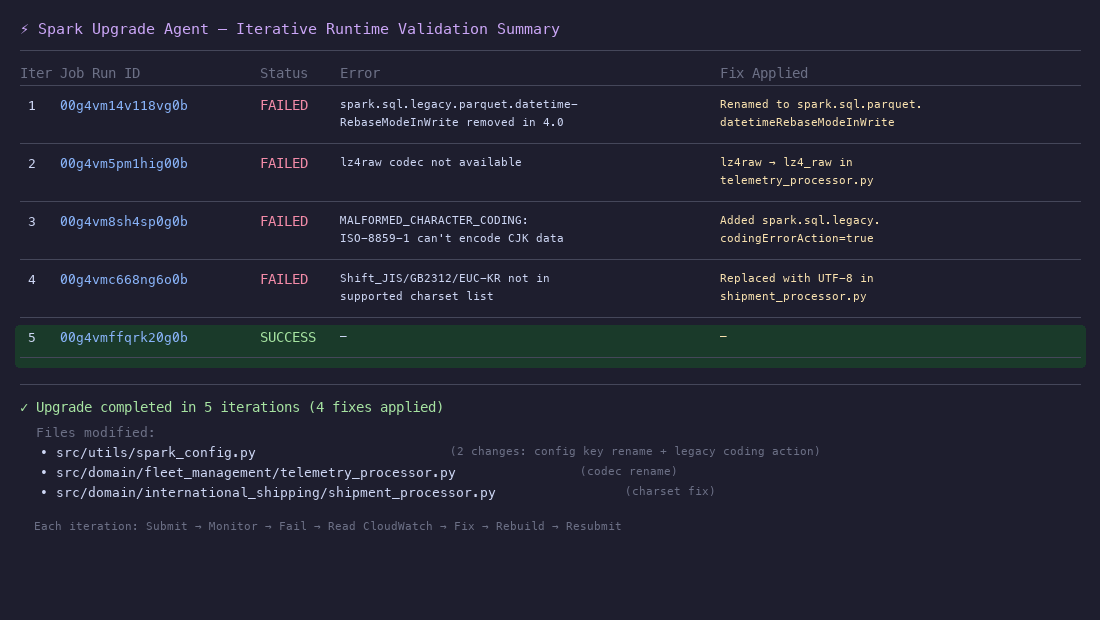
In this post, we walk through a hands-on PySpark migration from Spark 3.5 to Spark 4.0 on Amazon EMR Serverless, using the AWS Spark Upgrade Agent. You’ll see how the agent iteratively validates your application on a live Amazon EMR Serverless application, automatically diagnosing and resolving failures from Amazon CloudWatch logs until the job succeeds. By the end, you have a multi-pipeline PySpark application running on Spark 4.0 with four distinct breaking changes resolved. The fixes include configuration key removals, codec renames, and stricter charset validation, all driven through natural language interaction in the Integrated Development Environment (IDE).
This is part 2 of a three-part series on how the AWS Spark Upgrade Agent can automate and simplify Spark upgrades.
In Part 1, we introduced the agent’s architecture and capabilities. This post walks through a complete PySpark migration from Spark 3.5 to Spark 4.0 on Amazon EMR Serverless.
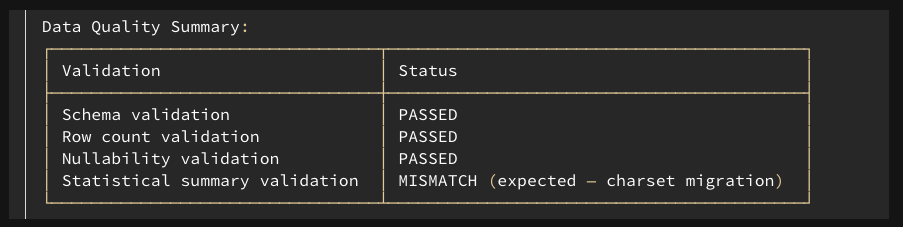
In the sections that follow, you will set up the prerequisites and infrastructure, explore the sample application, run the iterative validation workflow on EMR Serverless, review data quality results, and generate a comprehensive upgrade summary.
Note: Because this upgrade is performed using the AWS Spark Upgrade Agent Model Context Protocol (MCP) server, an agentic artificial intelligence (AI) system, the agent might take different paths to reach the same successful outcome. The workflow demonstrated here represents one successful upgrade path. The key takeaway is the end-to-end workflow: generating an upgrade plan, iteratively validating on Amazon EMR Serverless, and producing a comprehensive upgrade summary.
1. Prerequisites and setup
This section covers the tools, infrastructure, and IDE configuration you need before starting the upgrade. To follow along, you need an AWS account with an AWS Identity and Access Management (AWS IAM) user or role that has permissions to deploy AWS CloudFormation stacks, create AWS IAM roles and policies, and create Amazon EMR Serverless applications. Intermediate knowledge of AWS Command Line Interface (AWS CLI), AWS CloudFormation, and Python is helpful.
1.1 Install Kiro CLI and local tools
In this post, we use Kiro CLI to demonstrate the upgrade workflow. You can use an MCP-compatible IDE or framework. Examples include VS Code with Cline, Cursor, Windsurf, and Claude Desktop, among others. To follow along with Kiro CLI, install it on your workstation. For more details on the installation and setup, refer to Setup for Upgrade Agent:
curl -fsSL https://cli.kiro.dev/install | bash
Run the following command and use your builder ID to log in:
kiro-cli login --use-device-flow
With the Kiro CLI installed and logged in, rather than installing the remaining tools manually, use Kiro CLI to set up and verify your prerequisites with the following prompt:
kiro-cli chat
> Install AWS CLI, Python 3.10, and uv on my system if they are not already installed
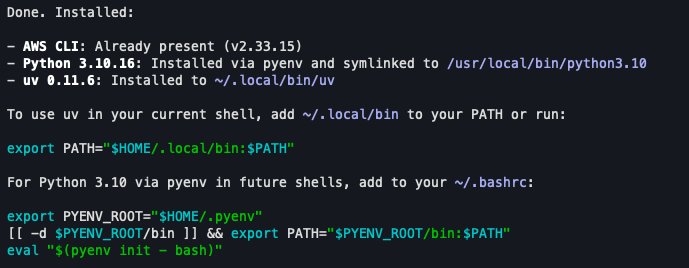
Output of AWS CLI and local tools install step.
These tools are needed for the upgrade workflow:
AWS CLI: Configured with a profile that has permissions to assume the AWS Identity and Access Management (AWS IAM) role created following.
Python 3.10+: Required to match the EMR 8.0 runtime.
Two AWS CloudFormation stacks create the required resources: an AWS IAM role, an Amazon Simple Storage Service (Amazon S3) staging bucket, an Amazon EMR Serverless application (Spark 4.0.1), and its execution role.
Stack 1 – AWS IAM role and Amazon S3 staging bucket:
The spark-upgrade-mcp-setup template creates the AWS IAM role and Amazon S3 staging bucket required by the upgrade agent. Choose the Launch Stack button for your Region. For additional Regions, see the full region list.
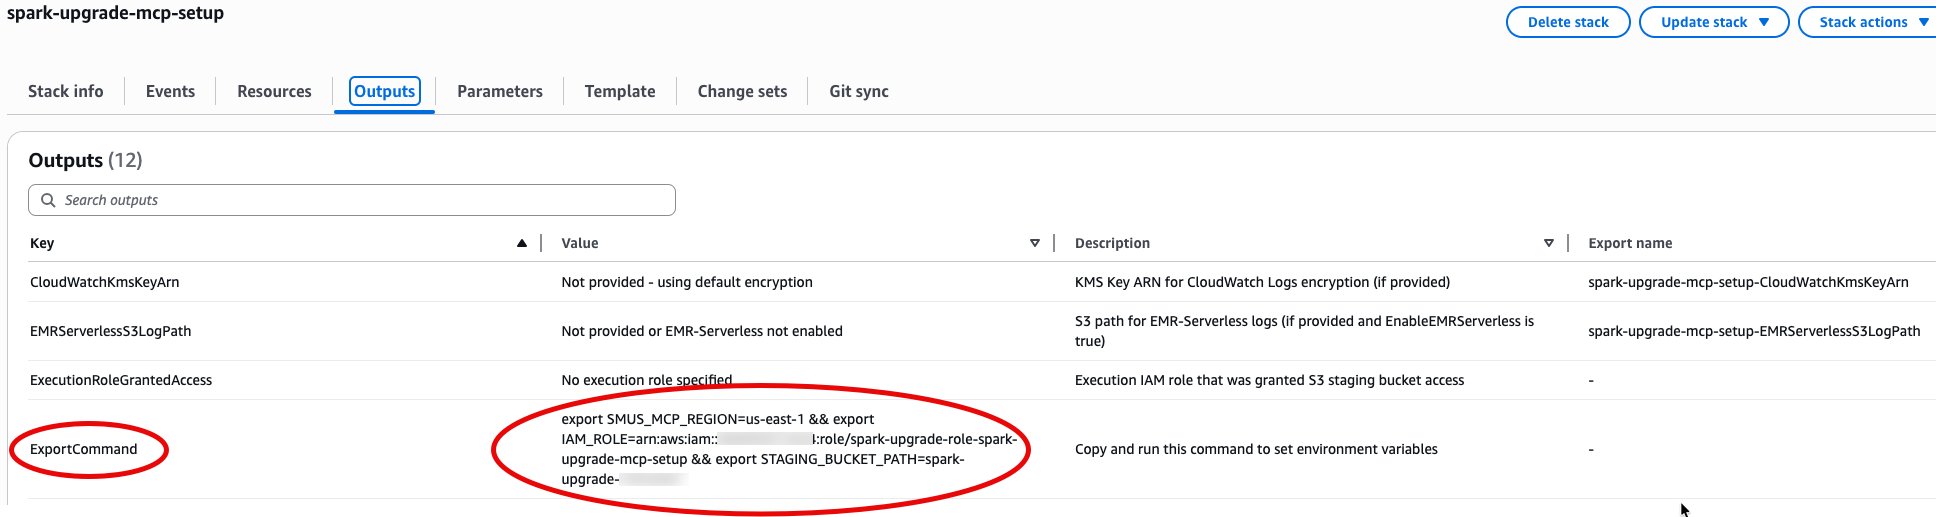
After deployment, open the AWS CloudFormation Outputs tab, copy the ExportCommand value, and run it in your terminal. This sets SMUS_MCP_REGION, IAM_ROLE, and STAGING_BUCKET_PATH automatically.
aws configure set profile.spark-upgrade-profile.role_arn ${IAM_ROLE}
aws configure set profile.spark-upgrade-profile.source_profile default
aws configure set profile.spark-upgrade-profile.region ${SMUS_MCP_REGION}
This creates two Amazon EMR Serverless applications: a source (Spark 3.5.0) for data quality baseline and a target (Spark 4.0.1) for upgrade validation, with a shared execution role. Both applications auto-stop after 15 minutes of idle time, so there is no cost when not in use. To upgrade between different Spark versions, override SourceReleaseLabel and TargetReleaseLabel with your target Amazon EMR release labels.
After the stack completes deployment, note the outputs:
For other MCP clients, refer to your IDE’s MCP configuration documentation and use the same server parameters shown previously.
Verify the connection: Start Kiro CLI and confirm the spark-upgrade tools are loaded:
$ kiro-cli chat
...
spark-upgrade (MCP):
- generate_spark_upgrade_plan          * not trusted
- update_build_configuration           * not trusted
- fix_upgrade_failure                  * not trusted
- run_validation_job                   * not trusted
- check_job_status                     * not trusted
...
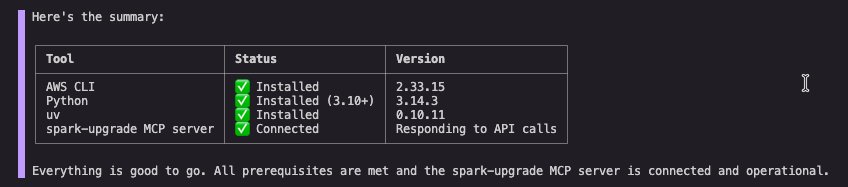
Tip: After Kiro CLI and the MCP server are configured, you can ask the agent to verify your setup. For example: “Check if I have AWS CLI, Python 3.10+, and uv installed, and confirm the spark-upgrade MCP server is connected.”
Output showing the status of each tool, AWS CLI, and MCP server.
Tip: Trust mode vs. confirm mode: When running the upgrade agent in Kiro CLI, you have two options:
Trust mode: Type t when prompted to approve a tool. The agent auto-approves subsequent uses of that tool without asking for confirmation. You can also use /tools trust-all to trust every tool at once for a fully autonomous experience.
Confirm mode: Type y for each individual tool invocation. This lets you review, verify, and approve every action before the agent runs it. If this is your first time using the agent, use confirm mode for full visibility.
2. Hands-on PySpark upgrade from Spark 3.5 to Spark 4.0
This section walks through the complete migration of a representative PySpark application from Amazon EMR Serverless 7.0.0 (Spark 3.5.0) to EMR Serverless with the emr-spark-8.0-preview release label (Spark 4.0.1), using the global_logistics_platform sample.
2.1 Sample project: global logistics platform
The sample application is a multi-domain PySpark data processing application with three pipelines:
Fleet management: Processes vehicle telemetry data (GPS tracking, fuel consumption, driver behavior scoring) using window functions, lag/lead operations, and statistical aggregations. Writes Parquet with lz4raw compression.
International shipping: Handles cross-border shipment documents with multi-language address standardization using character encoding functions (encode/decode with charsets like Shift_JIS, GB2312, EUC-KR), and processes carrier manifests with ISO-8859-1 encoding.
Historical compliance: Processes regulatory audit records spanning centuries (including pre-1582 Julian calendar dates), requiring legacy datetime rebasing for Parquet writes.
Before diving into the upgrade, here are the four specific breaking changes present in this code base that the agent discovers and resolves entirely through runtime validation:
#
Incompatibility
File(s)
1
Legacy Parquet configuration key removed:spark.sql.legacy.parquet.datetimeRebaseModeInWrite removed in Spark 4.0. Must use spark.sql.parquet.datetimeRebaseModeInWrite.
spark_config.py
2
Parquet compression codec rename:lz4raw codec renamed to lz4_raw in Spark 4.0.
telemetry_processor.py
3
Stricter charset encoding validation: Spark 4.0 tightened encode() behavior. Encoding CJK (Chinese, Japanese, Korean) characters to ISO-8859-1 now throws MALFORMED_CHARACTER_CODING. In Spark 3.x this silently replaced unmappable chars with ?. Restored via spark.sql.legacy.codingErrorAction.
spark_config.py
4
Character encoding restrictions:encode()/decode() in Spark 4.0 supports US-ASCII, ISO-8859-1, UTF-8, UTF-16BE, UTF-16LE, UTF-16, and UTF-32. Code uses Shift_JIS, GB2312, EUC-KR.
shipment_processor.py
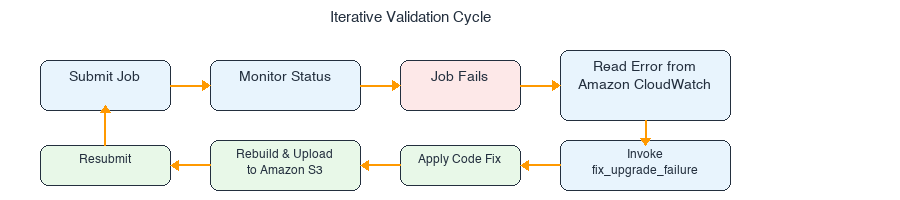
The agent resolves each of these through iterative runtime validation on EMR Serverless: submitting the job, diagnosing failures from Amazon CloudWatch logs, applying fixes, and resubmitting until the job succeeds.
2.3 Step 1: Invoke the upgrade agent
Open the project in Kiro CLI and enter the following prompt:
Upgrade my Spark application in the current directory from EMR serverless version 7.0.0 to EMR serverless version 8.0.0.
Use Amazon EMR Serverless target app-id <YOUR-TARGET-APP-ID> and execution role
<YOUR-EXECUTION-ROLE-ARN> for validation.
Use source Amazon EMR Serverless app-id <YOUR-SOURCE-APP-ID> for data quality baseline.
Store artifacts at s3://${STAGING_BUCKET_PATH}/spark4-upgrade/python/
Enable data quality validation
Tip: The SourceApplicationId, TargetApplicationId, and ExecutionRoleArn are in the Outputs of the spark-emr-serverless-upgrade AWS CloudFormation stack you deployed in Section 1.2.
The agent invokes generate_spark_upgrade_plan, scans the project structure, identifies the Spark version mapping (EMR 7.0.0 → Spark 3.5.0, EMR 8.0.0 → Spark 4.0.1), and produces a structured upgrade plan with an Analysis ID for traceability.
The agent presents the plan and asks for confirmation. Type y to approve the tool invocation, or t to trust that tool for the rest of the session.
You have an option to save the plan as a local JSON file for future reference or to resume the upgrade at a later point, so go ahead and ask Kiro to save it locally. Provide the AWS CLI profile that you have configured on your system. Use the following prompt to provide these inputs:
Yes I would like to save the plan to a local file and use spark-upgrade-profile
2.4 Step 2: Build and package
The agent validates the Python project compiles successfully, then packages it for Amazon EMR Serverless deployment:
Runs py_compile on each .py file to verify syntax.
Creates src.zip containing the src/ directory (preserving the import structure used by from src.utils import ...).
Uploads src.zip, main.py, and sample input data to the Amazon S3 staging path.
# What the agent does behind the scenes:
zip -r src.zip src/
aws s3 cp main.py s3://<YOUR-BUCKET>/spark4-upgrade/python/<ANALYSIS-ID>/source/main.py
aws s3 cp src.zip s3://<YOUR-BUCKET>/spark4-upgrade/python/<ANALYSIS-ID>/source/src.zip
aws s3 cp data/sample/ s3://<YOUR-BUCKET>/spark4-upgrade/python/<ANALYSIS-ID>/input/ --recursive
No external dependencies (no requirements.txt), so no virtual environment is needed. If your project has external dependencies in a requirements.txt, the agent will package them into a virtual environment archive and include it in the EMR Serverless submission parameters.
2.5 Step 3: Data quality baseline on source application
Before migrating the code, the agent establishes a data quality baseline by running the original (pre-upgrade) code on the source Amazon EMR Serverless application (Spark 3.5.0 / EMR 7.0.0). This captures the expected output that the upgraded application must match.
The agent submits the job to the source application with data quality check enabled:
The agent monitors the source run via check_job_status until it completes successfully. This baseline output is stored for comparison after the target validation succeeds.
2.6 Step 4: Iterative runtime validation on target application
This is the core of the upgrade. The agent submits the unmodified application to the target Amazon EMR Serverless application (Spark 4.0.1), and every incompatibility is discovered, diagnosed, and fixed through runtime failures. The agent drives the entire fix cycle by submitting to EMR, reading errors from Amazon CloudWatch logs, applying fixes, rebuilding, and resubmitting.
The agent presents the proposed Amazon EMR Serverless job configuration for your review before each submission. Type y to approve.
The first submission fails immediately at SparkSession initialization:
org.apache.spark.sql.AnalysisException:
The SQL config 'spark.sql.legacy.parquet.datetimeRebaseModeInWrite' was removed
in the version 4.0.0. Use 'spark.sql.parquet.datetimeRebaseModeInWrite' instead.
The Historical Compliance pipeline configures spark.sql.legacy.parquet.datetimeRebaseModeInWrite for handling pre-1582 Julian calendar dates. Spark 4.0 removed the legacy. prefix from this configuration key.
The agent calls fix_upgrade_failure, which identifies the migration rule and recommends the fix:
File:src/utils/spark_config.py
# Before
.config("spark.sql.legacy.parquet.datetimeRebaseModeInWrite", "LEGACY")

# After
.config("spark.sql.parquet.datetimeRebaseModeInWrite", "LEGACY")
After applying the fix, the agent rebuilds src.zip, re-uploads to Amazon S3, and resubmits the job.
The resubmitted job fails with a new error, which confirms progress:
pyspark.errors.exceptions.captured.IllegalArgumentException:
[CODEC_NOT_AVAILABLE.WITH_AVAILABLE_CODECS_SUGGESTION]
The codec lz4raw is not available.
Available codecs are brotli, uncompressed, lzo, snappy, lz4_raw, none, zstd, lz4, gzip.
SQLSTATE: 56038
The Fleet Management pipeline’s telemetry_processor.py uses lz4raw as the Parquet compression codec. Spark 4.0 renamed this to lz4_raw (with an underscore).
org.apache.spark.SparkRuntimeException:
[MALFORMED_CHARACTER_CODING]
Invalid value found when performing `encode` with ISO-8859-1
SQLSTATE: 22000
The International Shipping pipeline’s process_carrier_manifests() method uses encode(..., 'ISO-8859-1') on data containing CJK (Chinese, Japanese, Korean) characters. Although ISO-8859-1 is in Spark 4.0’s supported charset list, it is a single-byte encoding that cannot represent CJK characters. In Spark 3.x, the Java charset encoder silently replaced unmappable characters with ?. Spark 4.0 tightened this behavior to throw MALFORMED_CHARACTER_CODING for unmappable characters.
The agent identifies the migration rule and adds a legacy compatibility configuration:
File:src/utils/spark_config.py
# Added to SparkSession builder
.config("spark.sql.legacy.codingErrorAction", "true")
This restores the Spark 3.x behavior where unmappable characters are silently replaced instead of throwing errors.
With the configuration added, the agent rebuilds and resubmits.
2.6.4 Fix 4: Character encoding restrictions (iteration 4)
The fourth submission fails with yet another encoding error:
org.apache.spark.SparkIllegalArgumentException:
[INVALID_PARAMETER_VALUE.CHARSET]
The value of parameter(s) `charset` in `encode` is invalid:
expects one of the iso-8859-1, us-ascii, utf-16, utf-16be, utf-16le, utf-32, utf-8,
but got Shift_JIS. SQLSTATE: 22023
The International Shipping pipeline’s standardize_addresses_with_charset() method uses Shift_JIS, GB2312, and EUC-KR charsets in encode()/decode() calls. Spark 4.0 restricts these functions to seven standard charsets. These regional charsets are not in the supported list.
The agent replaces the unsupported charsets with UTF-8:
The three pipelines (Fleet Management, International Shipping, and Historical Compliance) complete on EMR Serverless with the emr-spark-8.0-preview release label (Spark 4.0.1).
2.7 Summary of the iterative runtime validation
The runtime validation loop is the core value of the upgrade agent. Here’s the complete iteration history:
Each iteration follows the same cycle:
Failures that would normally require manual log analysis, root cause investigation, and code patching are resolved automatically by the agent in this workflow.
3. Data quality validation
With both the source baseline (Section 2.5) and the upgraded target run (Section 2.6) completed successfully, the agent performs data quality validation to verify the migration hasn’t changed your application’s output. This is the key advantage of including the source application in your upgrade prompt: the agent can compare outputs from both Spark versions side by side.
3.1 Data quality comparison
The agent invokes get_data_quality_summary to compare the outputs across four dimensions:
Schema validation: Confirms column names, data types, and column ordering match between source and target outputs.
Row count validation: Verifies no data loss or duplication during migration.
Nullability validation: Detects changes in null handling.
The preceding image shows the data quality summary.
Three of four checks pass cleanly. The statistical summary validation detects a mismatch in the shipper_address column of the customs_declarations output: the max and min summary values differ between source and target.
3.2 Understanding and resolving the mismatch
This mismatch is a direct consequence of Fix 4 (Section 2.6.4). The original code ran addresses through a Shift_JIS/GB2312/EUC-KR → UTF-8 roundtrip that produced garbled text, because the intermediate regional charset corrupted multi-byte UTF-8 characters. The upgraded code uses UTF-8 → UTF-8, preserving addresses faithfully. The mismatch reflects improved data quality, not a regression.
Schema, row counts, and nullability matched exactly: the difference is limited to string values that were previously garbled. No further action is needed. The upgraded application is production-ready.
Expected behavior: Character encoding migrations might change string values, although they preserve semantic meaning. When data quality validation reports mismatches, trace each one back to a specific code change. If the mismatch is explained by a required migration fix (as here), verify the new behavior is correct and document it. If a mismatch cannot be explained, investigate before promoting to production.
4. Upgrade summary
After the agent completes the entire upgrade workflow, it produces a comprehensive upgrade summary following a structured template. This summary lets you review the job configuration updates, code modifications with diffs and file references, relevant migration rules applied, and data quality validation status.
Here is the summary the agent produced for this upgrade:
Upgrade plan
Compile and build project with current Spark 3.5.0: validated that Python files compile successfully.
Run baseline validation on source EMR Serverless (00g4vhvt1lhtrs09) with Spark 3.5.0: established data quality baseline.
Run target validation on target EMR Serverless (00g4vhvt3np1bj09) with Spark 4.0.1: fixed 4 issues iteratively across 4 validation attempts.
Compare data quality between source and target runs: detected expected mismatch in shipper_address.
Generate and persist upgrade summary.
Upgrade result
Upgrade completed with data validation enabled. Data validation detected an expected mismatch in the shipper_address column because of the charset encoding migration from unsupported charsets (Shift_JIS, GB2312, EUC-KR) to UTF-8.
Dependency changes
No external dependencies were changed in this project (no requirements.txt).
Job configuration changes
Parquet datetime rebase configuration key renamed.
Migration rule: In Spark 4.0, the legacy datetime rebasing SQL configurations with the prefix spark.sql.legacy are removed. The SQL configuration spark.sql.legacy.parquet.datetimeRebaseModeInWrite was removed in the version 4.0.0. Use spark.sql.parquet.datetimeRebaseModeInWrite instead.
Legacy coding error action enabled.
Change: Added spark.sql.legacy.codingErrorAction set to true.
Migration rule: In Spark 4.0, the encode() and decode() functions raise MALFORMED_CHARACTER_CODING error when handling unmappable characters. In Spark 3.5 and earlier versions, these characters are replaced with garbled text. To restore the previous behavior, set spark.sql.legacy.codingErrorAction to true.
Error: [INVALID_PARAMETER_VALUE.CHARSET] charset in encode is invalid: expects one of iso-8859-1, us-ascii, utf-16, utf-16be, utf-16le, utf-32, utf-8, but got Shift_JIS.
Applied changes: src/domain/international_shipping/shipment_processor.py: Replaced Shift_JIS, GB2312, EUC-KR with UTF-8 for shipper and consignee address encoding.
Data mismatch: 1. The shipper_address column max summary value changed in customs_declarations output. This is expected because of the charset encoding migration from Shift_JIS/GB2312/EUC-KR to UTF-8. 2. The shipper_address column min summary value changed in customs_declarations output for the same expected cause.
5. Conclusion
The AWS Spark Upgrade Agent turns a traditionally time-consuming PySpark migration into an automated, iterative workflow. For the Global Logistics Platform sample, the agent identified and resolved four distinct Spark 4.0 breaking changes: legacy Parquet configuration key removal, compression codec renames, stricter charset encoding validation, and character encoding restrictions. Each fix was applied across three domain processors, through natural language interaction in the IDE.
Every incompatibility was discovered through runtime validation on Amazon EMR Serverless. The agent submitted the unmodified application to the target application, and each failure revealed the next breaking change:
The spark.sql.legacy.parquet.datetimeRebaseModeInWrite configuration removal, which crashes SparkSession initialization.
The lz4raw → lz4_raw codec rename, which fails when Parquet writes run.
ISO-8859-1 encoding of CJK characters: ISO-8859-1 is a valid Spark 4.0 charset, so the failure surfaces only when the code runs against real multi-language data, because Spark 4.0 tightened charset encoding validation to reject unmappable characters.
Shift_JIS/GB2312/EUC-KR charsets removed from Spark 4.0’s supported charset list entirely.
The agent diagnosed each error from Amazon CloudWatch logs, applied the fix, rebuilt, and resubmitted without manual intervention beyond approving each step. The data quality validation then confirmed that the upgraded application produces equivalent output on Spark 4.0.1: schema, row counts, and nullability matched exactly. The one difference, in the shipper_address column, resulted from the charset migration from regional encodings to UTF-8, which actually improved data quality by eliminating garbled text from incorrect encoding roundtrips. With each mismatch traced back to a specific, understood code change, the upgraded application is production-ready.
Running JMS applications on on-premises brokers or Apache ActiveMQ requires manual patching cycles, capacity planning for peak loads, and maintaining high availability across multiple data centers. With Amazon MQ version 4 and above, you can migrate your existing JMS applications without rewriting your messaging layer, removing weeks of rewrite work.
This post shows you how to migrate your JMS applications and walks through a complete setup, from creating the broker to sending and receiving messages. You will also see a real-world scenario: migrating an existing Apache ActiveMQ workload to an Amazon MQ broker running RabbitMQ. The post covers configuration changes, monitoring with Amazon CloudWatch, and validation steps to make sure that your migration succeeds.
Amazon MQ version 4 and above includes built-in support for the RabbitMQ JMS Client and the JMS Topic Exchange plugin. The RabbitMQ JMS Client and JMS Topic Exchange plugin work together, allowing your existing JMS applications to connect using familiar JMS APIs. You update the connection factory configuration and broker endpoint. Your business logic, message producers, consumers, and listeners stay exactly as written.
Understanding JMS and AMQP
How the RabbitMQ JMS Client works
Use the RabbitMQ JMS Client to connect your Java application to Amazon MQ. The client translates your JMS API calls (javax.jms or jakarta.jms) into AMQP 0-9-1 messages that the broker understands.
Advanced Message Queuing Protocol (AMQP) defines how messages are formatted and transmitted across the network at the wire level. This means that non-Java services can consume the same messages using native AMQP clients, making the protocol language-agnostic
JMS version support
Migrate at the JMS version that your application already uses. The client supports JMS 1.1, 2.0, and 3.1 (Jakarta Messaging), so you don’t need to upgrade your application code before migrating brokers. The client integrates with Spring Framework and Spring Boot applications without requiring custom bean factories or application context configuration.
Because the JMS abstraction layer sits between your application and the broker, most migrations require only a connection factory change, not a logic rewrite.
RabbitMQ JMS Topic Exchange plugin
Your existing publish/subscribe patterns work without client-side routing logic. The JMS Topic Exchange plugin adds server-side support for JMS topic semantics, handling topic routing and SQL-based message selection directly in the broker.
The plugin handles SQL-based message selection (JMS selectors like OrderType = `Electronics` AND Priority > 5) and topic hierarchies with wildcard pattern matching (* for single level, # for multiple levels). Your application uses standard JMS topic APIs (createTopic(), setMessageSelector()) without additional filtering logic.
Getting started
This walkthrough shows you how to set up Amazon MQ and connect your existing JMS application. You will create a broker, configure the connection factory, and send and receive messages.
Prerequisites
You need an existing JMS application built on Apache ActiveMQ or another JMS provider to migrate. If you don’t have one, you can still follow Steps 1–5 to create a broker and test the connection pattern. Before you begin, confirm that you have the following in place:
An active AWS account
AWS Command Line Interface (AWS CLI) installed. For instructions, see Installing the AWS CLI.
Java 11 or later installed on your local development environment.
An AWS Identity and Access Management (IAM) principal (user or role) with the AmazonMQFullAccess managed policy attached.
Maven or Gradle for dependency management.
Amazon MQ broker charges apply based on instance type and usage. Review the Amazon MQ pricing page before you start.
Step 1: Create an Amazon MQ for RabbitMQ broker
The following command creates a single-instance broker running RabbitMQ 4.2 on an mq.m7g.medium instance.
Replace <broker-name> with the name that you want to give to the broker. Replace <username> and <password> as described in the create-broker CLI documentation. After the command runs successfully, the command line displays the BrokerArn and BrokerId.
Note: This command creates a publicly accessible broker for demonstration purposes only. For production workloads, create brokers in private subnets within your VPC and restrict access using security groups. Don’t use the –publicly-accessible flag. For more information, see Security best practices for Amazon MQ.
Choose the dependency that matches your application’s current JMS version. If your imports reference javax.jms packages, use version 2.12.0. If your imports reference jakarta.jms packages (JMS 3.1 / Jakarta EE 9+), use version 3.4.0.
Store your broker credentials in AWS Secrets Manager before configuring the connection factory. This keeps credentials out of your source code and configuration files.
Publish/subscribe (topic) for one-to-many broadcast:
try (JMSContext context = connectionFactory.createContext()) {
	Topic topic = context.createTopic("orders.electronics");
	context.createProducer().setProperty("MessageType", "Broadcast").send(topic, "New electronics order received!");
	System.out.println("Published message to topic: orders.electronics");
}
Message properties(OrderType, MessageType) are JMS headers that consumers can use for filtering. These properties become AMQP message headers when transmitted to the broker.
Step 5: Receive messages asynchronously
To receive messages asynchronously, attach a MessageListener to a consumer. The listener fires each time a message arrives.
Queue consumer:
Asynchronous consumers process messages in a background thread without blocking your main application logic. The MessageListener callback fires each time a message arrives, allowing your application to handle messages as they’re delivered rather than polling with receive().
try (JMSContext context = connectionFactory.createContext()) {
	Queue queue = context.createQueue("orders");
	JMSConsumer consumer = context.createConsumer(queue);
	consumer.setMessageListener(message -> {
		if (message instanceof TextMessage) {
			try {
				System.out.println("Received: " + ((TextMessage) message).getText());
			} catch (JMSException e) {
				e.printStackTrace();
			}
		}
	});

	System.out.println("Listening for messages on queue: orders");

	// Keep the consumer active for 30 seconds
	Thread.sleep(30000);
}
The Thread.sleep(30000) call keeps the consumer active for 30 seconds.
Use case: Migrating an ActiveMQ Workload to Amazon MQ for RabbitMQ
Migrate your Apache ActiveMQ applications to Amazon MQ by updating four configuration points. Your business logic, message producers, consumers, and listeners stay exactly as written. This walkthrough uses a real JMS 1.1 application with a centralized broker configuration class to show precisely which lines change and which remain identical.
Apache ActiveMQ powers messaging infrastructure for thousands of Java applications worldwide. If you run JMS applications on ActiveMQ, you can migrate to Amazon MQ for RabbitMQ with minimal code changes. The following steps demonstrate a complete migration using an application that includes a centralized broker configuration class, a message producer, and a message consumer.
Step 1: Update the Maven dependency
Replace the ActiveMQ client dependencies with the RabbitMQ JMS client in your pom.xml. The rabbitmq-jms artifact includes the RabbitMQ AMQP client and JMS API as transitive dependencies, so a single entry replaces both ActiveMQ artifacts.
The rabbitmq-jms artifact pulls in the RabbitMQ AMQP client and the JMS API as transitive dependencies, so a single entry replaces both ActiveMQ artifacts.
Step 2: Update the broker configuration
If your application centralizes connection details in a shared configuration class, that class is the only file that needs to change. The queue name and everything else your application references remain the same.
Before (ActiveMQ):
// BrokerConfig.java - ActiveMQ version
public final class BrokerConfig {
	// OpenWire endpoint
	public static final String BROKER_URL = "tcp://localhost:61616";
	public static final String USERNAME = "[PASSWORD]";
	public static final String PASSWORD = "[PASSWORD]";
	public static final String QUEUE_NAME = "demo.queue";
	private BrokerConfig() {}}
After (Amazon MQ):
// BrokerConfig.java - Amazon MQ version

import com.fasterxml.jackson.core.type.TypeReference;import com.fasterxml.jackson.databind.ObjectMapper;
import software.amazon.awssdk.regions.Region;
import software.amazon.awssdk.services.secretsmanager.SecretsManagerClient;
import software.amazon.awssdk.services.secretsmanager.model.GetSecretValueRequest;
import software.amazon.awssdk.services.secretsmanager.model.GetSecretValueResponse;
import java.util.Map;

public final class BrokerConfig {
	// AMQPS endpoint (TLS required by Amazon MQ)
	public static final String BROKER_URL = "amqps://b-c8352341-ec91-4a78-ad9c-a57f23f235bb.mq.us-west-2.on.aws:5671";

	// Queue name carries over unchanged
	public static final String QUEUE_NAME = "demo.queue";

	// Secret name in AWS Secrets Manager
	private static final String SECRET_ID = "dev-rabbitmq";
	private static final Map<String, String> CREDENTIALS = loadCredentials();
	public static String getUsername() {return CREDENTIALS.get("username");}
	public static String getPassword() {return CREDENTIALS.get("password");}
	private static Map<String, String> loadCredentials() {
		try (SecretsManagerClient client = SecretsManagerClient.builder().region(Region.US_WEST_2).build()) {
			GetSecretValueResponse response = client.getSecretValue(GetSecretValueRequest.builder().secretId(SECRET_ID).build());
			ObjectMapper mapper = new ObjectMapper();
			return mapper.readValue(response.secretString(), new TypeReference<Map<String, String>>() {});
		} catch (Exception e) {
			throw new RuntimeException("Failed to load broker credentials from Secrets Manager", e);
		}
	}
	private BrokerConfig() {}}
Two things changed in this file compared to the ActiveMQ version: the protocol prefix (tcp:// to amqps://) and the host and port (OpenWire on 61616 to AMQP over TLS on 5671). The queue name is identical. Credentials are no longer stored as static string constants. Instead, loadCredentials() retrieves them from AWS Secrets Manager at startup, and getUsername() and getPassword() expose them to the rest of the application. This follows AWS security best practices and streamlines credential rotation.
Step 3: Update the message producer
The producer requires two changes: the import statement and the factory instantiation. Every JMS API call after the factory (createConnection, createSession, createProducer, send) is identical to the ActiveMQ version.
import com.rabbitmq.jms.admin.RMQConnectionFactory;
import javax.jms.*;

public class MessageProducer {

	public static void main(String[] args) {
		Connection connection = null;
		try {
			RMQConnectionFactory factory = new RMQConnectionFactory();
			factory.setUri(BrokerConfig.BROKER_URL);
			factory.setUsername(BrokerConfig.getUsername());
			factory.setPassword(BrokerConfig.getPassword());

			// Everything below this line is identical to the ActiveMQ version
			connection = factory.createConnection();
			connection.start();
			Session session = connection.createSession(false, Session.AUTO_ACKNOWLEDGE);
			Destination destination = session.createQueue(BrokerConfig.QUEUE_NAME);
			javax.jms.MessageProducer producer = session.createProducer(destination);
			producer.setDeliveryMode(DeliveryMode.PERSISTENT);
			for (int i = 1; i <= 5; i++) {
				TextMessage message = session.createTextMessage("Hello from Amazon MQ - message #" + i);
				producer.send(message);
				System.out.println("Sent: " + message.getText());
			}
			producer.close();
			session.close();
		} catch (JMSException e) {
			e.printStackTrace();
		} finally {
			if (connection != null) {
				try {
					connection.close();
				} catch (JMSException ignored) {}
			}
		}
	}
}
The import changes from org.apache.activemq.ActiveMQConnectionFactory to com.rabbitmq.jms.admin.RMQConnectionFactory. The factory construction switches from a constructor that accepts credentials and URL to a no-arg constructor with explicit setter calls. Credentials are now retrieved from AWS Secrets Manager through BrokerConfig.getUsername() and BrokerConfig.getPassword(). That is the complete change set for the producer.
Step 4: Update the message consumer
The consumer follows the same pattern as the producer. Swap the factory class and import, update the credential calls, and keep everything else.
import com.rabbitmq.jms.admin.RMQConnectionFactory;
import javax.jms.*;

public class MessageConsumer {
	public static void main(String[] args) {
		Connection connection = null;
		try {
			RMQConnectionFactory factory = new RMQConnectionFactory();
			factory.setUri(BrokerConfig.BROKER_URL);
			factory.setUsername(BrokerConfig.getUsername());
			factory.setPassword(BrokerConfig.getPassword());

			// Everything below this line is identical to the ActiveMQ version
			connection = factory.createConnection();
			connection.start();
			Session session = connection.createSession(false, Session.AUTO_ACKNOWLEDGE);
			Destination destination = session.createQueue(BrokerConfig.QUEUE_NAME);
			javax.jms.MessageConsumer consumer = session.createConsumer(destination);
			System.out.println("Waiting for messages on queue: " + BrokerConfig.QUEUE_NAME);
			Message message;
			while ((message = consumer.receive(10000)) != null) {
				if (message instanceof TextMessage) {
					TextMessage textMessage = (TextMessage) message;
					System.out.println("Received: " + textMessage.getText());
				}
			}
			consumer.close();
			session.close();
		} catch (JMSException e) {
			e.printStackTrace();
		} finally {
			if (connection != null) {
				try {
					connection.close();
				} catch (JMSException ignored) {}
			}
		}
	}
}
The import changes from org.apache.activemq.ActiveMQConnectionFactory to com.rabbitmq.jms.admin.RMQConnectionFactory. The factory construction switches to a no-arg constructor with explicit setter calls, and BrokerConfig.USERNAME / BrokerConfig.PASSWORD are replaced with BrokerConfig.getUsername() / BrokerConfig.getPassword(). The session creation, queue lookup, consumer setup, and message processing loop are identical to the ActiveMQ version.
Configuration
The following table summarizes the changes required when migrating from Apache ActiveMQ.
ActiveMQ
Amazon MQ for RabbitMQ
Maven dependency
activemq-client 5.18.6
rabbitmq-jms 2.12.0
Connection factory class
ActiveMQConnectionFactory
RMQConnectionFactory
Import package
org.apache.activemq
com.rabbitmq.jms.admin
Broker URL format
tcp://host:61616
amqps://broker-id.mq.region.on.aws:5671
Protocol
OpenWire
AMQP 0-9-1
Port
61616 (OpenWire)
5671 (AMQP over TLS)
TLS
Optional
Required
Credentials
Plain text / JNDI
AWS Secrets Manager (recommended)
Virtual host
N/A
/ (default)
JMS version support
JMS 1.1
JMS 1.1, 2.0, 3.1 (Jakarta)
Queue/Topic names
demo.queue
demo.queue (no change)
JMS API calls
Standard JMS 1.1
Standard JMS 1.1 (no change)
Validating the migration
Run your application against Amazon MQ for RabbitMQ in a staging environment before directing production traffic to the new broker. Verify that messages flow correctly, consumers process as expected, and no data loss occurs during cutover.
The RabbitMQ management console provides real-time visibility into broker operations. Access it through the ConsoleURL from your broker details. The console shows queue depths, consumer counts, and message rates. Use it during testing to identify routing or throughput issues before production deployment
The console displays jms.durable.queues and jms.durable.topic exchanges. The JMS client creates these automatically when your application creates queues and topics, so no manual exchange configuration is required.
Monitoring with Amazon CloudWatch
Amazon MQ publishes broker metrics to Amazon CloudWatch with no additional configuration needed. This gives you persistent monitoring and alerting that works alongside the rest of your AWS observability setup, beyond what the RabbitMQ management console provides in real time.
After your JMS messages reach the Amazon MQ for RabbitMQ broker, they’re transported as AMQP messages, which means standard RabbitMQ operational best practices apply. Keep queue depth low to avoid memory pressure and consumer lag. Follow message durability and reliability guidelines to prevent message loss during broker restarts. For connection management, review broker setup and connection best practices to avoid connection churn.
Set Amazon CloudWatch alarms on MessageCount and ConnectionCount first. A rising queue depth with a stable or dropping consumer count is an early signal of a processing bottleneck. A sudden drop in connections can indicate a client configuration issue that’s more straightforward to catch before it affects production traffic.
Clean up
To avoid ongoing charges after testing, delete the Amazon MQ broker and Secrets Manager secret using the AWS CLI.
Broker deletion is permanent and can’t be undone. Amazon MQ removes all messages, configurations, and user credentials. Leaving the broker running incurs hourly charges based on the instance type, plus storage costs for message data retained on the broker.
Conclusion
In this post, we walked you through how to migrate your JMS applications. We also walked through a complete setup, from creating the broker to sending and receiving messages. Migrating the broker is the straightforward part. The more significant question is what you do next. After your JMS application is running on Amazon MQ for RabbitMQ, you have access to native AMQP clients, which means non-Java services can start consuming the same messages without a JMS layer. A Java-centric messaging system becomes a shared event backbone that service can participate in. The migration is a starting point, not just a lift-and-shift.
You can use Amazon Cognito user pools to add sign-up and sign-in functionality to your web and mobile applications. You can authenticate users directly with Amazon Cognito managed accounts using passwords, passwordless flows, or custom authentication flows, or let users federate in through external identity providers (IdP) using SAML, OpenID Connect, or social providers such as Google, Facebook, Sign in with Apple, or Login with Amazon. For consumers, identity federation means fewer passwords to remember and a smoother sign-in experience. For business-to-business (B2B) software as a service (SaaS) providers, it means your tenants’ organizations keep control of their own identities rather than managing credentials on their behalf. But federation can also introduce challenges for enterprises and application developers. What happens when your enterprise customer’s SAML provider sends hundreds of group memberships that exceed attribute size limits? Or when your ecommerce customer forgets they already have an account and tries to sign in with a different social provider, creating duplicate records?
In this blog post, I introduce the inbound federation Lambda trigger for Amazon Cognito, a new feature that gives you programmatic control over federated authentication flows. This AWS Lambda trigger intercepts the federated authentication response immediately after your external identity provider responds to Cognito, so you can transform, filter, and enrich user attributes before the user profile is created and user attributes are mapped in your user pool.
Understanding the inbound federation Lambda trigger
The inbound federation Lambda trigger is invoked after your Amazon Cognito user pool has received and verified the response from the external IdP. The request payload for the federated IdP response is then sent from Cognito to your Lambda function and you will receive the following information:
The common parameters of Amazon Cognito Lambda triggers (including userPoolId and clientId)
Which external IdP was used (for example, providerName)
The providerType (SAML, OIDC, Login with Amazon, and so on)
Attribute data from the external IdP specific to the user signing in
The specific format of this attribute data depends on the provider type, view the Inbound federation Lambda trigger parameters section in the docs to learn more. If the external IdP is a SAML provider, you will receive a JSON key-pair listing of the user’s attributes from the IdP assertion. If the external IdP is an OIDC provider (or social provider), you will receive the access token and attribute data from the /userinfo endpoint, along with an ID token if one was provided. See Figure 1 for a detailed flow of a federated sign-in with an Amazon Cognito user pool configured to use the inbound federation Lambda trigger.
Figure 1: Sequence flow of a federated login configured with the inbound federation Lambda trigger
The user begins using the application but is required to sign in first.
The managed login is rendered, and the user can select which IdP they want to sign in with. If identifiers are used with SAML or OIDC providers, the user enters their email address and Amazon Cognito looks up the domain of their provided email and routes them to the appropriate IdP.
Alternatively, the managed login can be bypassed by the client providing the identity_provider request parameter.
Amazon Cognito sends the authentication request to the appropriate IdP.
The external IdP challenges the user to sign in.
The user completes the sign-in process required by the external identity provider.
The challenge response is sent to the external IdP.
The IdP verifies that the sign-in is successful. If there are any subsequent challenges, such as multi-factor authentication (MFA), additional rounds of authentication challenges and responses take place. This is determined by the configuration and settings of the external IdP.
The external IdP sends a response to the Amazon Cognito user pool, and Cognito validates the cryptographic signature and that it hasn’t been tampered with.
Amazon Cognito sends attribute data from the IdP to the inbound federation Lambda function
Attribute data for the authenticated user and the common parameters for Amazon Cognito are available for the Lambda function to add, modify, or suppress according to your requirements.
Your added, modified, or suppressed attributes are returned to Amazon Cognito. These are attribute values that map to the user’s profile in Cognito—whether the user profile was just created or is being updated for a returning user.
Continuing the OAuth 2.0 authorization code grant, Amazon Cognito sends an authorization code to the client.
The client then calls the /token endpoint with the authorization code. Note: It’s a security best practice to use confidential clients and to use OAuth 2.0 Proof Key for Code Exchange (PKCE) extension whenever possible.
An access, ID, and refresh token is returned to the client.
The user has signed into the application. ID tokens can be used to identify who the user is (authentication), and access tokens can be used to determine what the user can do (authorization).
Common federation challenges and use cases
Federation introduces complexity that varies depending on your use case. For B2B and SaaS applications, you’re often not in control of your customers’ IdPs, including what attributes they send or how they format them. As an example, an enterprise customer will configure their SAML response to include every group a user belongs to. This could be hundreds of groups or long group identifiers, and if the group membership of the user is mapped to an Amazon Cognito attribute, this can lead to a scenario where the Cognito attribute size limit is exceeded, causing federated sign-ins to fail.
Challenges for business-to-customer (B2C) applications can differ from B2B use cases. For B2C applications, organizations shouldn’t be required to think about identity providers. The ability to sign-up and sign-in should be seamless for consumer-facing applications. Customers visiting a consumer-facing application might create an account with email and password, forget they created created it, and then later try signing in with Facebook (or other social provider). Without proper account linking in Amazon Cognito, you then have multiple user records for the same user, which could lead to fragmented purchase history and a frustrating customer experience.
Both B2B and B2C use cases might need to look up external data just prior to completing the sign-in process, such as additional roles and access for B2B users or looking up active orders for B2C users. Another example could be the need to normalize data just prior to storing it in the user profile within the Amazon Cognito user pool or even discarding personally identifiable information (PII) prior to storing it in your Cognito user pool.
With the inbound federation Lambda trigger, you can handle these B2B and B2C use cases programmatically, and do so without requiring modification of your applications or coordinating IdP-specific changes with external IdPs. In this section, I dive deeper into two common use cases: oversized group attributes, common with B2B customers, and automated account linking, common with B2C customers.
Use case 1: Filtering oversized group attributes
If you have B2B and SaaS use cases, it’s a common practice to use group membership from the IdP to determine the level of access you have within the SaaS service. This is a great way to still provide some access control back to the enterprise customers themselves. The groups can be used to represent the roles a user will have or for some form of coarse-grained authorization. However, your customers might inadvertently send a large number of groups a user is a member of, thus leading to an oversized attribute payload.
Another common scenario is where the syntax and format of group name a user belongs to can arrive in various formats across different IdPs; such as a canonical name (for example, example.com/groups/myApp-readOnly), a distinguished name (common with LDAP based systems and such as cn=myApp-readOnly,OU=groups,DC=example,DC=com), or a plain text string (such as myApp-readOnly). Instead of having downstream authorization logic to accommodate different variations of a group name, you can now normalize how groups are represented prior to storing the user’s attribute data using the inbound federation Lambda trigger.
To expand this, imagine your enterprise customer uses a SAML IdP, such as Active Directory Federation Services (AD FS), in front of Active Directory (AD). When their users authenticate, AD FS sends a groups attribute containing every AD group the user belongs to. For users in large organizations, this can be hundreds of groups, and the attribute is mapped to an Amazon Cognito attribute, this could result in a string that exceeds 2,048-character limit per attribute of Cognito. Authentication would fail in this scenario, ultimately leading to support tickets because enterprise customers would be unable to sign in. Even if certain users didn’t exceed this limit, because of a smaller number of group memberships, this would result in the collection and storing of unnecessary data in your Cognito user pool.
Previously, you would need to work with your customer’s IT department to modify their SAML configuration to filter groups at the source—a process that could take weeks and require multiple approval cycles because it involves a change to the federation configuration. Especially for SaaS customers, this isn’t a scalable approach because you could integrate with hundreds of external IdPs. With the inbound federation Lambda trigger, you can solve this by filtering the groups to only those relevant to your application and normalizing the nomenclature of these groups. The following Lambda function filters the groups attribute to include only groups relevant to your application and normalizes the names of groups.
// Configure the group prefix to filter on (e.g. "App1-", "myApp-", etc.)
// Change this to match the prefix your IdP uses for relevant group names.
const GROUP_PREFIX = process.env.GROUP_PREFIX || 'myApp-';

// The SAML attribute/claim name that contains group membership.
// Common values: "groups", "memberOf", "http://schemas.xmlsoap.org/claims/Group", etc.
const GROUP_ATTRIBUTE = process.env.GROUP_ATTRIBUTE || 'groups';

/**
 * Extracts the short group name from common IdP formats:
 *   - Plain text:       "myApp-readOnly"
 *   - Leading slash:    "/myApp-readOnly"
 *   - Canonical/URL:    "example.com/groups/myApp-readOnly"
 *   - Distinguished name (DN): "cn=myApp-readOnly,OU=groups,DC=example,DC=com"
 * Returns the last meaningful segment so all formats normalize to "myApp-readOnly".
 */

function extractGroupName(raw) {
  let name = raw.trim();

  // Some IdPs prefix group names with "/" to indicate a top level group — strip it before format detection
  if (name.startsWith('/')) {
    name = name.substring(1);
  }

  // DN format — extract the CN (common name) value
  if (/^cn=/i.test(name) || /,\s*(ou|dc)=/i.test(name)) {
    const cnMatch = name.match(/^cn=([^,]+)/i);
    return cnMatch ? cnMatch[1].trim() : name;
  }

  // URL / path format — take the last segment after the final "/"
  if (name.includes('/')) {
    const segments = name.split('/').filter(Boolean);
    return segments[segments.length - 1];
  }

  return name;
}
export const handler = async (event) => {
  try {
    console.log('Full event:', JSON.stringify(event, null, 2));
    console.log('Provider type:', event.request?.providerType);

    // Initialize the response structure
    event.response = event.response || {};

    if (event.request?.providerType?.toLowerCase() === "saml") {
      const samlResponse = event.request.attributes?.samlResponse;

      if (samlResponse) {
        console.log('Original SAML Attributes:', JSON.stringify(samlResponse, null, 2));

        // Build the attribute map — you MUST include every attribute you want Cognito to retain. Anything omitted from userAttributesToMap is dropped.
        const mappedAttributes = {};

        Object.keys(samlResponse).forEach(key => {
          if (key === GROUP_ATTRIBUTE) {
            // Parse the groups JSON string from the SAML assertion
            let groupsArray = [];
            try {
              groupsArray = JSON.parse(samlResponse[GROUP_ATTRIBUTE]);
            } catch (error) {
              console.error(`Error parsing ${GROUP_ATTRIBUTE}:`, error);
            }

            // Normalize each group name, then filter to the configured prefix
            const normalizedGroups = groupsArray.map(extractGroupName);
            const filteredGroups = normalizedGroups.filter(group =>
              group.startsWith(GROUP_PREFIX)
            );

            console.log(`Original ${GROUP_ATTRIBUTE}:`, groupsArray);
            console.log(`Normalized ${GROUP_ATTRIBUTE}:`, normalizedGroups);
            console.log(`Filtered ${GROUP_ATTRIBUTE}:`, filteredGroups);

            // Only include the groups attribute if there are matching groups
            if (filteredGroups.length > 0) {
              mappedAttributes[GROUP_ATTRIBUTE] = filteredGroups.map(group => `'${group}'`).join(', ');
            }
          } else {
            // Pass all other SAML attributes through unchanged
            mappedAttributes[key] = samlResponse[key];
          }
        });

        event.response.userAttributesToMap = mappedAttributes;
        console.log('Response to Cognito:', JSON.stringify(event.response, null, 2));
      }
    }

    // For any unhandled provider type (or missing samlResponse), this intentionally does NOT set userAttributesToMap and tells Cognito to keep all original IdP attributes unchanged (no-op).

    // To handle OIDC or social providers, add additional logic here using event.request.attributes.idToken, .userInfo, and/or .tokenResponse.

    return event;
  } catch (error) {
    console.error('Error in Lambda:', error);
    throw error;
  }
};
This approach reduces a large group list to only what is applicable to your application. Authentication succeeds, and you maintain control over your user pool’s data without depending on external configuration changes.
Use case 2: Automatic account linking
The second use case addresses a challenge that’s particularly common in B2C facing ecommerce or any consumer-facing applications; although it can also be applicable to B2B scenarios. Imagine you’re running an online retail store. A customer creates an account with their email and password to make a purchase. A few months later, they return to your site but forgot they already created an account and they see the Login with Amazon button and decide to sign in this way. Without account linking, Amazon Cognito creates a new federated user because these are technically distinct accounts, and now this customer has two separate accounts with different purchase histories and saved preferences.
This fragmentation creates a poor customer experience and complicates your business operations. You can’t see the customer’s complete purchase history, loyalty points are split across accounts, and your analytics show two distinct customers instead of one.
The inbound federation Lambda trigger can be used to solve this by automatically linking federated identities to existing local accounts based on email address. While account linking can also be implemented in a pre-sign-up Lambda trigger, the inbound federation trigger runs on every federated sign-in, not just the first, giving you access to the latest IdP attributes and the ability to apply linking logic continuously rather than only at initial account creation. If no local Amazon Cognito account exists, you can create one and then link the social provider account to it. The local account can serve as the primary identity, ensuring consistent JSON Web Tokens (JWTs) regardless of how the user signs in. The following is an example of an inbound federation Lambda trigger that can help address this use case.
import {
  CognitoIdentityProviderClient,
  ListUsersCommand,
  AdminCreateUserCommand,
  AdminLinkProviderForUserCommand
} from "@aws-sdk/client-cognito-identity-provider";

const client = new CognitoIdentityProviderClient();

export const handler = async (event) => {
  try {
    console.log('Full event:', JSON.stringify(event, null, 2));

    const { userPoolId, request, userName } = event;
    const { providerName, providerType, attributes } = request;

    // Extract email and profile attributes based on provider type
    const { email, givenName, surname } = extractAttributes(providerType, attributes);

    if (!email) {
      console.error('No email found in federated response');
      return event;
    }

    console.log(`Processing federated login for email: ${email}, provider: ${providerName} (${providerType})`);

    // Check if a local user exists with this email
    const existingUser = await findLocalUserByEmail(userPoolId, email);

    if (existingUser) {
      console.log(`Found existing local user: ${existingUser.Username}`);
      if (isAlreadyLinked(existingUser, providerName, userName)) {
        console.log(`Federated identity ${providerName}:${userName} is already linked to ${existingUser.Username}, skipping link`);
      } else {
        await linkFederatedUser(userPoolId, existingUser.Username, providerName, userName);
      }
    } else {
      console.log('No existing local user found, creating new one');
      const newUsername = await createLocalUser(userPoolId, email, givenName, surname);
      await linkFederatedUser(userPoolId, newUsername, providerName, userName);
    }

    return event;

  } catch (error) {
    console.error('Error in account linking Lambda:', error);
    throw error;
  }
};


/**
 * Check if the federated identity is already linked to the local user by inspecting the identities attribute from the ListUsers response.
 */
function isAlreadyLinked(user, providerName, federatedUsername) {
  const identities = user.Attributes?.find(a => a.Name === 'identities');
  if (!identities?.Value) return false;

  try {
    const parsed = JSON.parse(identities.Value);
    return parsed.some(id => id.providerName === providerName && id.userId === federatedUsername);
  } catch {
    return false;
  }
}

/**
 * Extract email and profile attributes based on provider type.
 * - SAML: attributes come from samlResponse
 * - OIDC/Social: attributes come from userInfo, falling back to idToken (if one exists)
 */
function extractAttributes(providerType, attributes) {
  if (providerType?.toLowerCase() === 'saml') {
    const saml = attributes?.samlResponse;
    return {
      email: saml?.email || null,
      givenName: saml?.givenName || '',
      surname: saml?.surname || ''
    };
  }

  // OIDC and social providers: prefer userInfo, fall back to idToken
  const userInfo = attributes?.userInfo;
  const idToken = attributes?.idToken;

  const source = userInfo?.email ? userInfo : idToken;

  return {
    email: source?.email || null,
    givenName: source?.given_name || '',
    surname: source?.family_name || ''
  };
}

/**
 * Find a local Cognito user (not EXTERNAL_PROVIDER) by email address.
 */
async function findLocalUserByEmail(userPoolId, email) {
  try {
    const command = new ListUsersCommand({
      UserPoolId: userPoolId,
      Filter: `email = "${email}"`
    });

    const response = await client.send(command);
    console.log('ListUsers response:', JSON.stringify(response, null, 2));

    if (!response.Users || response.Users.length === 0) {
      return null;
    }

    // Find the first user that is a true local account (not a federated-only profile)
    const localUser = response.Users.find(u => u.UserStatus !== 'EXTERNAL_PROVIDER');
    return localUser || null;
  } catch (error) {
    console.error('Error finding user by email:', error);
    throw error;
  }
}

/**
 * Create a new local Cognito user without a password.
 * With passwordless (email OTP) enabled on the user pool, the user is created with UserStatus=CONFIRMED and no FORCE_CHANGE_PASSWORD state.
 */
async function createLocalUser(userPoolId, email, givenName, surname) {
  try {
    const userAttributes = [
      { Name: 'email', Value: email }
    ];

    if (givenName) userAttributes.push({ Name: 'given_name', Value: givenName });
    if (surname) userAttributes.push({ Name: 'family_name', Value: surname });

    const command = new AdminCreateUserCommand({
      UserPoolId: userPoolId,
      Username: email,
      UserAttributes: userAttributes,
      MessageAction: 'SUPPRESS'
    });

    const response = await client.send(command);
    console.log(`Created local user: ${email}`, JSON.stringify(response, null, 2));

    return email;
  } catch (error) {
    console.error('Error creating local user:', error);
    throw error;
  }
}

/**
 * Link a federated user identity to a local Cognito user.
 * The local user becomes the primary profile — all future JWTs will represent this local user regardless of sign-in method.
 */
async function linkFederatedUser(userPoolId, localUsername, providerName, federatedUsername) {
  try {
    const command = new AdminLinkProviderForUserCommand({
      UserPoolId: userPoolId,
      DestinationUser: {
        ProviderName: 'Cognito',
        ProviderAttributeValue: localUsername
      },
      SourceUser: {
        ProviderName: providerName,
        ProviderAttributeName: 'Cognito_Subject',
        ProviderAttributeValue: federatedUsername
      }
    });

    const response = await client.send(command);
    console.log(`Linked federated user ${federatedUsername} to local user ${localUsername}`);
    console.log('Link response:', JSON.stringify(response, null, 2));

    return response;
  } catch (error) {
    if (error.name === 'AliasExistsException' || error.message?.includes('already linked')) {
      console.log(`User already linked: ${error.message}`);
      return;
    }
    console.error('Error linking federated user:', error);
    throw error;
  }
}
Every federated sign-in will invoke the inbound federation Lambda trigger, and the logic is straightforward. When a user authenticates with an external identity provider, the trigger extracts their email from the federated response and searches the user pool for a local Cognito account with that same email. If one exists—such as if the user originally signed up with email and password—the Lambda function links the federated identity to that existing local account. If no local account exists, the trigger creates one on the fly as a passwordless account (confirmed, suppressing any emails, and ready for passwordless email one-time passcode (OTP) sign-in), then links the federated identity to it. In both cases, the local account is set as the primary profile. This means the user’s JWTs always carry the same sub-claim regardless of how they sign in—directly, or through Google, Facebook, or SAML—your application sees one consistent identity. The preceding Lambda trigger is also smart enough to check whether a linked account already exists before making the call, so returning users who’ve already been linked don’t generate unnecessary API calls. And because the local account supports passwordless authentication, a user who first arrived through federation can later sign in directly with an emailed OTP—or even add a password later through your applications account settings. The local account is always the anchor.
Best practices
As you implement these patterns, keep a few best practices in mind. Your Lambda function must be completed within 5 seconds, so optimize for speed to help ensure the federated sign-in process is able to successfully complete. If you’re making external calls within the inbound federation Lambda function, like Amazon DynamoDB queries or API requests, implement caching where possible. Handle errors gracefully—if your Lambda function throws an exception or an error, authentication could fail for the user. Consider logging the error and returning the original event back to Amazon Cognito rather than failing authentication for a legitimate user attempting to sign in. Here are some additional best practices for working with Lambda functions.
For the account linking use case, automatic linking relies on matching the email from the federated identity to a local account. However, there are scenarios where this match won’t exist. For example, Apple’s Hide My Email feature generates a unique alias for each app, so the federated email won’t match any existing local account. This is an effective privacy feature but it also blocks the ability to automatically link accounts. In cases like these, your application will need to implement a user-initiated account linking flow, such as prompting the user to verify ownership of both email addresses before calling the AdminLinkProviderForUser API to complete the link.
Monitor your Lambda function performance using Amazon CloudWatch metrics. Set up alarms for errors, timeouts, and throttling so you can respond quickly if issues arise. I also recommend capturing sample event payloads from a CloudWatch log group during your initial development and deployment—these will be valuable for local testing and debugging which can lead to quicker resolution if issues arise in your production environment. This is especially important as different IdPs (namely SAML and OIDC providers) may respond with varying attribute and value syntaxes. Consider implementing CloudWatch alarms to alert your security and operational teams if authentication failures spike, which could indicate an attempted attack, misconfiguration, or provide insight into further optimization of your inbound federation Lambda trigger.
Conclusion
In this post, you learned about the new inbound federation Lambda trigger for Amazon Cognito and how it can solve various use cases. You walked through two common federation challenges and reviewed some sample code to help resolve those challenges. For B2B and SaaS applications, the inbound federation Lambda trigger gives you control when dealing with oversized attributes from external identity providers (such as group membership) without requiring coordination with enterprise IT teams. For B2C and consumer-facing applications, it enables seamless account linking across multiple authentication methods, creating a unified customer experience.
The new Lambda trigger works with SAML, OIDC, and supported social providers, and is available now in AWS Regions where Amazon Cognito is available. To learn more about the new Lambda trigger and others, see the Amazon Cognito Developer Guide.
What federation challenges are you facing in your applications? I’d love to hear about your use cases in the comments below and over at AWS re:Post.
When you develop SQL against Amazon Redshift and Amazon Athena, you spend time finding the right tables across hundreds of databases, writing complex joins and aggregations, debugging failed queries without context from previous attempts, and re-specifying filters for every new question. Amazon SageMaker Data Agent in Query Editor takes a different approach. You describe what you need in natural language, and the Data Agent generates the SQL. It references your actual tables through AWS Glue Data Catalog, proposes step-by-step plans for complex questions, retains context across your session, and offers one-click error recovery with Fix with AI. In this post, you learn how to use Data Agent in Query Editor to explore data, build multi-step analyses, recover from errors, and summarize results using a public education dataset.
Solution overview
You can go from a natural language question to executable SQL in seconds. Data Agent in Query Editor provides a conversational interface with direct access to your AWS data environment, so you spend less time on query mechanics and more time on analysis. Data Agent in Query Editor focuses specifically on SQL development against Amazon Redshift and Amazon Athena. (For Python, SQL, and PySpark across broader analytical and machine learning (ML) workloads, use Data Agent in notebooks.)
Data Agent provides four key capabilities:
Catalog-aware SQL generation. You don’t need to browse catalog structures or memorize schema details. Data Agent reads your table metadata directly.
Querybook and session context. You build on previous work. Data Agent uses context from your earlier queries and results.
Step-by-step planning. You review and approve a structured plan before Data Agent generates SQL.
Fix with AI. You recover from failed queries with one click.
Data Agent integrates with AWS Glue Data Catalog and reads your actual table names, column types, descriptions, and relationships, so generated SQL references your real tables. Each follow-up question builds on your current Query Editor session—the SQL cells in your querybook, the active connection, your selected cell, and execution results from previously run cells. For complex requests, Data Agent produces a structured plan that specifies which data to retrieve, how to aggregate it, and what filters to apply. You review and approve each step before Data Agent proceeds. When a query fails, choose Fix with AI to get a corrected query based on the error and the failed cell’s context.
[Figure 1: The Query Editor Fix with AI panel, showing a corrected SQL query ready for your review.]
Walkthrough: Education data analysis
In this section, you use Data Agent in Query Editor to analyze California schools data and identify where SAT improvement investment has the most impact. The walkthrough covers four tasks:
Explore available data.
Build a multi-step analysis plan.
Summarize insights from your queries.
Recover from a failed query.
The same workflow applies to your own data, whether you are analyzing sales figures, operational metrics, or financial records.
The California schools dataset contains SAT score results, school demographic information, and county-level data for public schools across California. The dataset includes tables that organize SAT scores by subject (reading, writing, math), school details (name, address, county, district), and enrollment figures. After you upload the data into your project database, you directly access the tables from Query Editor through your Amazon Athena or Amazon Redshift Lakehouse connection.
Prerequisites
To complete this walkthrough, you need intermediate SQL knowledge and basic familiarity with the AWS Management Console. You don’t need prior AWS Glue experience, but familiarity with data catalogs (centralized metadata repositories) helps.
You can choose one of two setup paths:
Quick start (5 minutes). SageMaker Unified Studio provides a sample database (sagemaker_sample_db) with pre-loaded data. To explore it, choose Data in the navigation pane, expand AwsDataCatalog, and select sagemaker_sample_db.
Full setup (30–45 minutes). Upload the California schools dataset into your project’s Lakehouse database. This dataset is publicly available from the California Department of Education. Download the SAT scores, school information, and county-level data files, then upload them through the SageMaker Unified Studio UI. In your project, go to Build, choose Query editor, right-click your project database in the Data explorer, and choose Create table. Drag and drop each CSV file to create the tables. SageMaker Unified Studio stores the data in the project-managed Amazon Simple Storage Service (Amazon S3) location, registers it in AWS Glue Data Catalog, and applies AWS Lake Formation governance automatically.
Running queries against Amazon Athena or Amazon Redshift might incur costs. For pricing details, refer to Amazon Athena pricing and Amazon Redshift pricing. For detailed setup instructions, refer to AWS Identity and Access Management (IAM)-based domains and projects. Before starting the walkthrough, you must have a SageMaker Unified Studio IAM-based domain with a project using the SQL analytics or All Capabilities project profile. The project automatically provisions an AWS Glue database, the required IAM role, and Athena or Redshift Lakehouse connections.
[Figure 2: The Data Explorer panel in Query Editor, showing the california_schools_db and sagemaker_sample_db tables.]
Explore available data. To start, enter the following prompt in the Data Agent panel:
Query my SAT scores from my california_schools_db
Data Agent searches AWS Glue Data Catalog, locates the relevant tables, and generates an initial exploratory query that retrieves SAT score records. It adds a SQL cell directly to your querybook.
Review the generated SQL in the comparison view, which highlights the proposed code.
Choose Accept, Reject, or Accept and run.
After you run the cell, the results appear inline, giving you a view of the data (column names, score ranges, and the number of records) before you write SQL.
[Figure 3: Data Agent returns an exploratory query for the california_schools_db tables, ready for your review.]
[Figure 4: The SQL query results appear beneath the cell after you choose Accept and run.]
Build a multi-step analysis plan. With the data explored, enter a more complex analytical question:
Identify which subjects need investment to improve SAT scores in the lowest-performing counties. Include school-level details with addresses.
Data Agent proposes a step-by-step plan before generating SQL. For this request, Data Agent breaks the question into three steps:
Aggregate SAT scores by county and subject to find performance patterns.
Filter to counties with a sufficient number of schools and rank the lowest performers.
Join school address data to produce a final detailed list.
Review the plan in the Data Agent panel and choose Run step-by-step to proceed.
[Figure 5: Data Agent proposes a multi-step plan with options to Cancel plan or Run step-by-step.]
Data Agent generates SQL for each step and adds it as a separate querybook cell. Review each cell’s SQL in the comparison view, then choose Accept and run to execute it. The results from each step are visible inline, so you can verify the intermediate output (county-level aggregations, the filtered ranking, and the final school list) before moving to the next step. When the steps are complete, your querybook contains the full analytical progression from raw scores to a detailed investment list.
[Figure 6: Each plan step produces a querybook cell that you can review and run independently.]
Summarize insights from your queries. After running the analysis, enter the following prompt:
Summarize the insights from my queries
Data Agent has context on your querybook, including the SQL and the query results from each cell. It generates a natural language summary: which counties are underperforming, which subjects (reading, writing, or math) need the most attention in each county, and how many schools appear on the investment list. This summary provides a starting point for a report or presentation.
[Figure 7: Data Agent summarizes insights from the accumulated query results in the querybook.]
Recover from a failed query. During the analysis, a generated query might produce an error, for example, referencing a column name that doesn’t match the schema or a join condition that returns unexpected results. When a cell fails, Query Editor displays the error message and a Fix with AI option.
Choose Fix with AI, and Data Agent reads the error in the context of the failed cell, then generates corrected SQL and updates the querybook cell. Run the corrected cell to verify the fix.
[Figure 8: After you choose Fix with AI, Data Agent is prompted to generate a corrected query for the failed cell.]
[Figure 9: Data Agent returns corrected SQL for you to review.]
Security and governance
Data Agent operates within your AWS environment and only accesses data that your IAM policies explicitly permit. Your existing IAM access controls and AWS Lake Formation permissions determine what data Data Agent can reach. To use Data Agent, your project role must have permissions to invoke specific Amazon DataZone APIs. For more information, refer to Actions, resources, and condition keys for Amazon DataZone.
Data Agent includes content filtering that prevents it from responding to off-topic requests, requests to reveal its system prompt, and requests for internal technical implementation details. Data Agent is restricted to AWS-related topics and English-language output.
Amazon SageMaker stores your natural language prompts and generated SQL in the AWS Region where you created your SageMaker Unified Studio domain. Data Agent doesn’t store your data, querybook context, or catalog metadata.
The walkthrough creates querybook cells in your Query Editor session but doesn’t provision standalone infrastructure. To remove the generated SQL cells, delete them from your querybook or delete the querybook itself.
If you uploaded the California schools dataset specifically for this walkthrough, remove the following resources to avoid ongoing charges:
SageMaker Unified Studio domain. If you created a domain solely for this walkthrough, delete it to stop incurring charges. Refer to the SageMaker Unified Studio administration guide for deletion steps.
Uploaded tables. In the Data explorer, right-click each table you created and choose Delete table to remove the data from your project database and the underlying S3 storage.
Amazon Athena query results. Amazon Athena stores query results in an S3 output location. Delete the query result files from that bucket, or delete the bucket if you created it solely for this walkthrough.
Amazon CloudWatch logs. If Amazon Athena queries generated CloudWatch log groups, delete those log groups to avoid storage charges.
Conclusion
Data Agent in Query Editor brings conversational, catalog-aware SQL development to your Amazon Redshift and Amazon Athena workloads. In this post, you explored unfamiliar data, built a multi-step investment analysis, recovered from query errors, and summarized findings through natural language prompts.
Data Agent works within your existing IAM and AWS Lake Formation security controls, keeps your data within your AWS environment, and retains context across your analytical workflow so each question builds on the last.
Get started with these next steps:
Run your first prompt. Open Query Editor in your SageMaker Unified Studio domain and enter Show me the top 10 tables in my catalog with the most columns. For setup, refer to the SageMaker Unified Studio getting started guide.
Add descriptions to your AWS Glue Data Catalog. Table descriptions and column-level business metadata improve the quality of generated SQL. For best practices, refer to Populating the AWS Glue Data Catalog.
Try a multi-step analysis. Enter Which product categories had declining revenue quarter-over-quarter, and which regions drove the decline? and review Data Agent’s plan step by step.
If you build notebooks for recurring tasks such as daily customer analysis, weekly report generation, or data quality checks in Amazon SageMaker Unified Studio, you’ve likely wanted to run them automatically on a schedule. Until now, there wasn’t a native way to do this. Teams had to manage orchestration separately, even though the interactive notebook experience was already in place. Now, notebook scheduling is available, so you can configure your production workloads to run automatically with minimal manual intervention.
In this post, we walk you through the new scheduling and orchestrating capabilities for notebooks in Amazon SageMaker Unified Studio. You will learn how to:
Trigger on-demand background runs, such as a model re-training job, without waiting at your desk.
Create recurring schedules for tasks such as nightly data freshness checks or weekly business reviews.
Parameterize notebooks so a single template can generate reports across different AWS Regions or customer segments.
Orchestrate multi-notebook workflows where one notebook’s output feeds into the next. For example, an extract, transform, and load (ETL) pipeline followed by a summary dashboard refresh.
Debug failed runs with AI-assisted troubleshooting.
Sample use case overview
In this walkthrough, you will take on the role of a logistics analyst who monitors shipping performance across carriers. The notebook loads shipping data from the ShippingLogs.csv dataset, identifies late deliveries, and generates a performance summary. You want to run this notebook every morning without manual intervention, reuse it across different carriers, and know when something goes wrong.
You will start by running a notebook in the background and viewing the results. Next, you will create a recurring schedule for daily runs, then parameterize the notebook to generate reports for different carriers. You will also orchestrate the notebook in a multi-step workflow and debug a failed run using AI-assisted troubleshooting.
Prerequisites
Before you begin, you need:
An Amazon SageMaker Unified Studio project with Notebooks enabled. See Set up IAM-based domains for permission requirements.
A sample dataset. We use the ShippingLogs.csv dataset, which contains shipping data including estimated and actual delivery times, carriers, and origins. You can download it from the Workshop Studio (the file is named ShippingLogs.csv on the linked page).
Setting up the notebook
Start by creating a new notebook in your SageMaker Unified Studio project. If you haven’t already, upload the ShippingLogs.csv file under the Shared tab in the Files panel.
In the first cell, we load and explore the dataset. To reference the file in code, select the file in the Shared tab and copy the Amazon Simple Storage Service (Amazon S3) URI shown in the file details. Alternatively, you can reference it with this code:
import pandas as pd
from sagemaker_studio import Project

# Initialize the project
proj = Project()

# Get the S3 root path
s3_root = proj.s3.root

df = pd.read_csv(s3_root + '/ShippingLogs.csv')
df.head()
The dataset contains columns including Carrier, ActualShippingDays, ExpectedShippingDays, ShippingOrigin, ShippingPriority, and OnTimeDelivery. Add a second cell to analyze shipping performance for a single carrier:
import matplotlib.pyplot as plt

carrier_data = df[df['Carrier'] == 'GlobalFreight']
# Flag late deliveries
carrier_data['is_late'] = carrier_data['ActualShippingDays'] > carrier_data['ExpectedShippingDays']
late_pct = carrier_data['is_late'].mean() * 100
# Visualize actual vs expected shipping days
plt.figure(figsize=(12, 4))
plt.hist(carrier_data['ActualShippingDays'] - carrier_data['ExpectedShippingDays'], bins=20, edgecolor='black')
plt.axvline(x=0, color='red', linestyle='--', label='On time')
plt.title(f'Shipping Delay Distribution - GlobalFreight ({late_pct:.1f}% late)')
plt.xlabel('Days Over Expected')
plt.ylabel('Number of Shipments')
plt.legend()
plt.show()
With the notebook working interactively, you’re ready to automate it.
Running a notebook asynchronously
To trigger an asynchronous run, open your notebook. In the notebook header, choose the menu on the Run all button, and then choose Run in background.
This captures a snapshot of the notebook in its current state and starts a run on a separate dedicated compute. You can continue working on other tasks or close the browser entirely. Your interactive session isn’t affected.
You will see a notification at the bottom of your screen confirming that the run started. To check the status of your run, choose View Run in the notification. This opens a view showing every background and scheduled run with its status, duration, and a link to view the full output.
You can choose to view the run details at any point to view results as cells run. The run details include three tabs:
Output: The notebook in read-only mode with cell results rendered, including dataframe outputs, visualizations, and print statements.
Parameters: The parameter values used for this run.
Logs: Run logs for debugging.
You can also access past runs by selecting the View Runs option in the notebook header.
Stopping an in-progress run
If you need to cancel a run, open the run, and choose Stop. The run terminates, and its status updates to reflect the cancellation.
What to know about background runs
Compute: Each background run uses its own dedicated compute, separate from your interactive session. Your interactive work isn’t interrupted.
Packages: The packages that you install through the notebook’s package manager will be available in your background runs. When you use !pip install in code cells, the asynchronous run installs those packages as well.
Local files: Background runs can’t access files stored locally in your notebook environment. Reference data from your project’s shared storage (Amazon S3) or connected data sources instead.
Startup time: Expect a few minutes of startup time while compute is provisioned and your environment is prepared.
Creating a recurring schedule
Now that you’ve confirmed asynchronous runs work correctly, you can automate the notebook on a schedule. Choose the schedule icon in the notebook header to open the schedule creation form.
Configure the following settings:
Schedule name: Enter a descriptive name, such as Daily Shipping Report.
Schedule type: Choose Recurring for repeated runs or One-time for a single future run.
Frequency: Define how often the notebook runs using a rate (for example, every one day) or a cron expression. Set the time zone and the start and end dates for the schedule. For example, set the schedule to run every day at 7:00 AM UTC starting tomorrow.
Flexible time window (optional): The number of minutes after the scheduled start time within which the run can be invoked. For example, with a 5-minute window, the notebook runs within 5 minutes of the start time.
Advanced settings:
Compute Instance: Keep the current settings or override with a different instance type for the asynchronous run to use.
Timeout: Set a maximum run duration to help prevent notebooks from running indefinitely. If left blank, it defaults to 60 minutes.
Choose Create.
The schedule appears in the Schedules tab of the activity panel. SageMaker Unified Studio creates an Amazon EventBridge Scheduler schedule for each schedule you configure.
Viewing schedule run history
To view past runs for a schedule, choose the schedule name in the Schedules activity panel. This opens the schedule details view, where you can see the list of runs triggered by that schedule, the duration of each run, and a link to open the notebook output for an individual run.
Editing and deleting schedules
To modify a schedule, choose Edit next to it in the Schedules panel. You can change the frequency, instance type, timeout, and other configuration fields. To pause or resume a schedule, choose Pause or Resume from the same menu. To remove a schedule, choose Delete from that menu. Deleting a schedule stops future runs but preserves historical run outputs in Amazon S3 for auditing purposes.
Parameterizing notebooks
With parameters, you can reuse a single notebook across different inputs without duplicating code. For example, you can run the same shipping performance report for each carrier by passing a different carrier name to each run.
Defining parameters
Open the Parameters activity panel and choose Add. Set the parameter name to carrier and the default value to GlobalFreight.
Using parameters in code
In your notebook, replace the second cell with the following code. This retrieves the carrier parameter value using the SageMaker Unified Studio Python SDK instead of the hardcoded value:
Creating schedules with different parameter values
Now create three schedules for the same notebook, each targeting a different carrier:
“daily-shipping-gf” with carrier = GlobalFreight.
“daily-shipping-mc” with carrier = MicroCarrier.
“daily-shipping-shipper” with carrier = Shipper.
When you view a historical run, a separate Parameters tab in the run output displays the parameter values that were active for that run.
You can also override parameter values when triggering an on-demand background run. Choose the menu on the Run all button, then choose Run with settings. You can keep the defaults or provide custom values for that run.
Orchestrating with Workflows
To combine notebooks into a multi-step pipeline, such as running a data calculation notebook before the shipping log notebook, you can use the Notebook Operator in the Workflows tool to orchestrate them.
To do this, choose the Add to workflows button under the options menu of the notebook header.
This takes you to the Workflows tool, adding a new Notebook Operator task with prefilled properties from your notebook. When configuring the Operator task:
Select the target notebook from the notebook menu.
Use the Parameters widget to pass notebook parameters into the run of the notebook.
Specify optional arguments such as the compute instance and timeout configuration for the run.
Workflows also supports polling for the status of a notebook run for a particular notebook using Notebook Sensor. In Workflows, you can add a new Sensor task by hovering on the edge of the existing Operator task, where a plus (+) button is displayed.
You can then search for and add the Notebook Sensor to the canvas.
When configuring the Sensor task, specify the notebook run ID within the text field. The Operator’s form field contains Jinja templating to retrieve the notebook run. If the Sensor is used within the same workflow as the Operator, this template can be copied to use within a Sensor to poll the notebook run. Select the target notebook from the notebook menu.
Within Workflows, you can configure notebook runs to emit outputs and use those outputs as inputs for subsequent notebook runs.
Building off of the previous shipping log notebook example, we will pass the carrier parameter from an upstream notebook’s output. Your shipping-logs-analysis notebook should be already set up.
Because the notebook depends on the carrier parameter, you can specify it in the Parameters panel.
Now, define a second notebook, calculate-best-carrier, which performs a calculation to determine our best carrier to use for shipping:
import pandas as pd
from sagemaker_studio import Project

# Initialize the project
proj = Project()

# Get the S3 root path
s3_root = proj.s3.root

df = pd.read_csv(s3_root + '/ShippingLogs.csv')
df.head()

carrier_stats = df.groupby('Carrier').agg(
    total=('OrderID', 'count'),
    late=('OnTimeDelivery', lambda x: (x == 'Late').sum())
).reset_index()
carrier_stats['late_pct'] = carrier_stats['late'] / carrier_stats['total'] * 100

best = carrier_stats.sort_values('late_pct', ascending=True).iloc[0]
best_carrier = best['Carrier']

print("Late % by carrier:")
print(carrier_stats.to_string(index=False))
print(f"\nBest carrier: {best_carrier} ({best['late_pct']:.1f}% late)")
To configure the calculate-best-carrier notebook’s outputs, you can choose the Variables panel. A new selector is available at the bottom of this panel which allows you to select variables to mark as outputs.
We want this notebook to emit the best_carrier variable.
Now, use the Add to workflows button as previously demonstrated to quickly add this notebook within a workflow. Chain a second Notebook Operator that points to our shipping-logs-analysis notebook. Because we specified a parameter dependency on carrier for this notebook, it’s available as an option in the Parameters widget menu.
When they’re chained, the notebook tasks detect the outputs set in upstream notebook runs. These outputs can be selected as keys within the Parameters widget of the Operator to pass into the run. This can be done recursively for an arbitrary number of Operator tasks. We can select the emitted best_carrier output from the calculate-best-carrier notebook.
You can now choose the Save button on the top left of the visual canvas and the Run button to start the workflow. When the workflow is completed, the specified notebook outputs are available in the Task Output panel and the notebook run result can be viewed in the Notebooks tool.
In a similar manner, the Notebook Sensor will also emit the notebook outputs from a particular notebook’s run which can be used within other tasks. This is useful when you want to retrieve outputs from a notebook run in another workflow.
Debugging a failed run with AI assistance
When viewing your past runs, you notice that a run from earlier today has a Failed status. Choose the failed run to open the notebook output in read-only mode.
In this example, suppose you incorrectly referred to column name ActualShippingDays as DeliveryDays. The run would fail with a KeyError: 'DeliveryDays' in the cell that computes late deliveries.
At the top of the failed run output, choose Troubleshoot with AI. Choosing the Troubleshoot with AI button lands you in the notebook with the Agent chat panel open.
The data agent analyzes the cell outputs, identifies the cell that errored, explains the root cause, and suggests a fix. In this case, it identifies that the column DeliveryDays doesn’t exist in the dataframe and suggests updating the code reference. You can review the change, then verify the fix by choosing Run in background from the Run all menu to trigger a test run before the next scheduled run.
Note: You can also use the Data Agent to create schedules and start notebook runs using natural language, without having to navigate.
Cleaning up
To avoid incurring future charges, delete the resources that you created in this walkthrough:
Delete any schedules that you created from the Schedules panel in your notebook.
Delete test notebooks if you don’t need them.
Navigate to the Workflows page and delete any workflows that you created during this walkthrough.
Your project’s Amazon S3 storage retains historical run outputs until you manually remove them.
Conclusion
In this post, we showed how to run notebooks in the background in Amazon SageMaker Unified Studio using background runs, schedules, parameterization, workflow orchestration, and AI-assisted debugging. Using a shipping logistics dataset, we demonstrated how a single notebook can be parameterized to generate performance reports for different carriers on independent schedules, all without duplicating code or managing extensive infrastructure.
To get started, open a notebook in your SageMaker Unified Studio project, choose the menu on the Run all button in the notebook header, and choose Run in background. For more advanced use cases, explore workflows in Amazon SageMaker Unified Studio to build multi-step data pipelines, or review the Amazon SageMaker Unified Studio User Guide for additional configuration options.
Oracle databases power mission-critical enterprise applications, making their continuous availability essential for business operations. Traditional Oracle high availability (HA) solutions require complex clustering software, expensive shared storage arrays, and specialized database administration teams. These conventional approaches often introduce single points of failure while demanding significant operational overhead.
Modern cloud architectures offer a transformative approach that combines Amazon FSx for NetApp ONTAP (FSxN) with Amazon EC2 Auto Scaling groups, automated AMI creation, AWS Lambda-driven orchestration, and AWS Systems Manager Parameter Store (SSM Parameter). This solution removes traditional Oracle HA complexities while delivering enterprise-grade availability, automated recovery, and makes sure new instances launch with the latest Oracle configuration.
This post shows how to build a highly available Oracle database architecture using FSxN shared storage, Auto Scaling groups with dynamic AMI updates, and serverless orchestration to help reduce recovery times with current configurations.
Solution overview
The solution uses multiple AWS services working together to create a comprehensive high availability architecture. FSxN Multi-AZ provides persistent shared storage spanning availability zones for Oracle database files, software, and configurations, so that data remains accessible when EC2 instances are replaced. Auto Scaling groups deliver automated instance lifecycle management with the latest AMI configurations, so failed instances are quickly replaced with identical configurations that can immediately access the existing Oracle database files on FSxN. AWS Backup creates AMIs that capture the latest Oracle host configurations including patches and settings, preserving the complete server state for consistent deployments. AWS Lambda extracts the AMI ID from backup recovery points and updates the SSM Parameter, orchestrating the entire configuration management workflow. Systems Manager Parameter Store stores the current AMI ID for Auto Scaling group launch templates, so new instances always launch with the most recent configuration and can immediately connect to the Oracle database on shared storage.
The following diagram shows the complete architecture with all AWS services and their interactions:
Key benefits include:
Recovery Time Objective (RTO): Can help achieve 2–5 minutes with latest Oracle configuration
Recovery Point Objective (RPO): Near-zero through synchronous Multi-AZ replication
Configuration consistency: New instances launch with identical Oracle host setup
Automated AMI management: Scheduled AMI creation with Parameter Store updates
Walkthrough
This walkthrough demonstrates implementing Oracle HA using Amazon FSx for NetApp ONTAP shared storage, AWS Backup-driven AMI creation, Lambda orchestration, and Auto Scaling groups with Parameter Store integration for configuration consistency and automated failover.
Prerequisites
For this walkthrough, you should have the following prerequisites:
An AWS account with appropriate permissions for Amazon FSx, Auto Scaling, EC2, Lambda, and Systems Manager
A VPC with subnets in at least two Availability Zones
Keep in mind that customers are responsible for their own Oracle licensing compliance.
An EC2 instance with Oracle database installed and configured
AWS Identity and Access Management (IAM) roles for AMI creation and cross-service communication
Basic knowledge of Oracle database administration and AWS automation
Assumptions
This post is a conceptual illustration of the architecture. Your specific implementation will vary based on your VPC layout, Oracle version, storage requirements, and organizational security policies.
We assume the reader is familiar with:
Creating and configuring Amazon FSx for NetApp ONTAP file systems through the AWS console
iSCSI concepts including initiators, targets, and multipath I/O
Oracle database startup and shutdown procedures
AWS Backup, Lambda, and Auto Scaling group fundamentals
For detailed step-by-step instructions on specific AWS services, refer to the additional resources section.
Step 1: Create an Amazon FSx for NetApp ONTAP file system
FSxN Multi-AZ provides the persistent shared storage foundation for this architecture. Unlike Amazon Elastic Block Store (Amazon EBS) volumes, which are bound to a single AZ, FSxN Multi-AZ replicates data synchronously across two AZs with automatic failover. This means that when an EC2 instance is replaced (whether in the same AZ or a different one), the new instance can immediately access the existing Oracle database files without restoring from backup.
To create the file system, navigate to the Amazon FSx console and select Amazon FSx for NetApp ONTAP as the file system type.
The critical configuration choice is selecting Multi-AZ deployment, which places an active file server in one AZ and a standby in another.
FSxN console showing Multi-AZ deployment type selection with preferred and standby subnets in separate availability zones.
After the file system is created, you need to set up a Storage Virtual Machine (SVM), which acts as a logical storage container providing data access to your Oracle instances. The SVM creation is done from the FSx console under your file system’s details.With the SVM in place, the next step is configuring iSCSI access. FSxN exposes iSCSI endpoints—these are IP addresses (one per AZ) that your EC2 instances use to connect to the storage over the iSCSI protocol. You can find these endpoint addresses in the FSx console under your SVM’s Endpoints tab.
SVM Endpoints tab showing iSCSI endpoint IP addresses for each availability zone. These addresses are used in the EC2 instance’s iSCSI discovery configuration.
The iSCSI setup involves creating iGroups (which define which EC2 instances can access the storage) and LUNs (logical storage units mapped to those groups) through the NetApp ONTAP CLI. On the EC2 side, you configure the iSCSI initiator to discover and connect to the FSxN endpoints, then mount the resulting block devices. Using multipath I/O with both endpoints makes sure that Oracle data remains accessible even during an AZ failover. For detailed iSCSI configuration steps, see mounting iSCSI LUNs on Linux clients.
A dedicated security group is required for FSxN access. At minimum, the security group must allow inbound traffic on ports 111 (NFS portmapper), 635 (NFS mountd), 2049 (NFS), 3260 (iSCSI), 4045–4046 (NFS lock), 443 (HTTPS for management), and 22 (SSH for ONTAP CLI). Restrict the source to only your Oracle EC2 instances’ security group.
Step 2: Set up AWS Backup for EC2 instance protection
AWS Backup captures the complete state of your Oracle EC2 instance. The key design choice here is using tag-based resource selection rather than specifying instance IDs directly. Because Auto Scaling groups replace instances (and generate new instance IDs), tag-based selection makes sure that any new instance with the correct tags are automatically included in the backup plan.Configure a backup plan with a frequency appropriate for your environment and set the resource assignment to select EC2 instances matching your application tag (for example, ‘Application: Oracle’).
AWS Backup resource assignment configured with tag-based selection. Any EC2 instances tagged with the application tag are automatically included in the backup plan.
Step 3: Configure Lambda for AMI management
When AWS Backup completes an EC2 backup, it creates an AMI as the recovery point. An Amazon EventBridge rule detects this completion event and triggers a Lambda function. The function extracts the AMI ID from the backup recovery point, updates the SSM Parameter Store parameter with the new AMI ID, and cleans up older AMIs to control storage costs.
Lambda function overview showing the EventBridge trigger, Python 3.11 runtime, and function description indicating its role in processing backup completions and updating AMI references in SSM.
This event-driven approach means the latest AMI is available without manual intervention. The Lambda function needs IAM permissions for EC2 (to manage AMIs), SSM (to update the parameter), and Backup (to read recovery point metadata).
EventBridge rule configured to match AWS Backup job completion events for EC2 resources, with the Lambda function as the target.
Step 4: Configure the Systems Manager Parameter Store
The SSM Parameter Store holds the current AMI ID that the Auto Scaling group’s launch template references. The parameter is created with the aws:ec2:image data type, which enables the launch template’s resolve:ssm: functionality, a feature that allows the launch template to dynamically resolve the AMI ID at instance launch time without requiring a template version update.
SSM Parameter Store showing the /oracle/ec2/ami-id parameter with aws:ec2:image data type. The “Last modified user” confirms the Lambda function is automatically updating this parameter after each backup cycle.
When Lambda updates this parameter after each backup cycle, the next instance launched by the Auto Scaling group will automatically use the latest AMI. This removes the operational burden of manually updating launch template versions.
Step 5: Set up an Auto Scaling Group with dynamic AMI
The launch template references the SSM parameter using the resolve:ssm: prefix for the AMI ID field. This is the mechanism that ties the entire automation pipeline together. The mechanism backups trigger AMI creation, AMI IDs flow into Parameter Store, and the launch template resolves the latest AMI at launch time.
Launch template AMI configuration showing the ‘resolve:ssm:’ prefix, which dynamically retrieves the latest AMI ID from Parameter Store at instance launch time.
The Auto Scaling group is configured with minimum, maximum, and desired capacity all set to 1. This is not traditional auto-scaling, it’s a self-healing pattern. The sole purpose is to detect when the Oracle instance becomes unhealthy and automatically launch a replacement. The health check grace period should be set to at least 300 seconds (5 minutes) to allow Oracle sufficient time to start before health checks begin evaluating the new instance.
The launch template also includes a User Data script that runs on each new instance. This script configures the iSCSI initiator, discovers and connects to the FSxN endpoints, mounts the Oracle data volumes, and starts the Oracle database through a systemd service. This automation makes sure that a replacement instance is fully operational without manual intervention.
Auto Scaling group configured with min=max=desired=1 across two availability zones, providing self-healing capability.
Test the complete workflow
To validate the architecture, simulate an instance failure by terminating the current Oracle EC2 instance.
The expected sequence is:
The Auto Scaling group detects the instance is unhealthy (within approximately 30 seconds)
A new instance launches from the latest AMI resolved from Parameter Store (approximately 2 minutes)
The User Data script connects to FSxN using iSCSI and starts Oracle (approximately 2–3 minutes)
The Oracle database is available and accepting connections (total elapsed: approximately 5 minutes)
Auto Scaling group Activity History showing the self-healing sequence — the unhealthy instance is terminated, and a replacement is launched automatically within seconds.
The new instance automatically inherits the application tags from the Auto Scaling group, which means AWS Backup includes it in the next backup cycle without manual configuration.
Cleaning up
To avoid incurring future charges, delete the resources:
Delete Lambda functions and EventBridge rules
Remove Parameters from Systems Manager Parameter Store
Delete AWS Backup plans and backup vault
Deregister created AMIs
Terminate Auto Scaling group instances
Delete the Amazon FSx for NetApp ONTAP file system
Conclusion
This architecture facilitates Oracle high availability with configuration consistency by combining FSxN persistent shared storage with automated AMI management and AWS Backup protection. The Lambda-driven AMI management from backup recovery points and Parameter Store integration helps make sure that replacement instances launched by Auto Scaling groups always use the latest Oracle host configuration and can immediately connect to the existing Oracle database files stored on FSxN. Replacements occur only when health checks fail. Organizations can target high availability while maintaining configuration consistency across instance replacements. The automated AMI management alleviates configuration drift and makes sure that disaster recovery scenarios restore Oracle instances with identical host-level configurations that can immediately access the persistent Oracle database on shared storage. Healthy instances continue running unchanged, with replacements occurring only, when necessary, because of health check failures.Next steps include implementing cross-Region AMI replication, adding AMI validation testing, and developing custom health checks that verify both Oracle database and host configuration consistency.
As you scale your use of Amazon Web Services (AWS), managing KMS keys becomes increasingly important. Whether you manage a handful of keys or thousands across multiple AWS accounts and AWS Regions, there’s often a need to audit key usage to help you meet compliance requirements, evaluate your risk posture, and optimize key management costs. However, determining which keys are actively in use and which have been sitting idle can be a time consuming and complex task.
To help with this, AWS Key Management Service (AWS KMS) has launched the GetKeyLastUsage API, a new feature that you can use to quickly determine when each key was last used for a cryptographic operation, significantly enhancing your audit capabilities and key lifecycle management. For more information, see Determine past usage of a KMS key.
Before this launch, the primary way to audit key usage was through AWS CloudTrail logs. CloudTrail captures every cryptographic operation by default, so the data is available. The difficulty is turning that data into actionable insight. You need to identify which keys to examine, query the right logs, and repeat that process frequently enough to maintain an accurate view. For the most recent 90 days, CloudTrail event history makes this manageable. Beyond that, you need to create a dedicated trail to deliver logs to Amazon Simple Storage Service (Amazon S3) for long-term retention, then query those logs using tools such as Amazon Athena to determine when a key was last used.
Determine when a key was last used
AWS KMS now provides a direct way to see when a key was last used for cryptographic operations. You can also see this information using the AWS Management Console for AWS KMS and the AWS Command Line Interface (AWS CLI).
The GetKeyLastUsage API returns the date and time of the most recent cryptographic operation performed with a KMS key, without requiring you to search through CloudTrail logs. The API returns the date and time of the last key operation, the type of operation performed, CloudTrail event ID, and KMS request ID. You can access this information for all customer-managed keys and AWS managed keys irrespective of key spec, key origin, key store, or key usage type.
In addition, you can restrict a key from being disabled or scheduled for deletion if it was recently used, by incorporating this usage information as a condition within the KMS key policy. See the Preventing accidental key deletion with policy controls section for implementation details.
About the tracking period
One of the important concepts you must understand before relying on the last usage information reported on a KMS key is the tracking period. The tracking period is the date from which AWS KMS began tracking cryptographic activity for the key. Tracking began on April 23, 2026, for most AWS Regions. Understanding the tracking period is critical because it determines whether the absence of usage information means a key has never been used or only hasn’t been used since tracking started.
For example, if you have a key created on January 1, 2026, and you check its usage, any cryptographic operations that occurred between January 1 and April 22 wouldn’t be captured in the usage information. Thus, you can’t conclude that it’s never been used, because it might have been used in the months before tracking began.
Getting started
There’s nothing to enable or additional configuration required to view usage information on last cryptographic operation performed on your KMS keys.
To view KMS key usage:
Go to the AWS KMS console and choose Customer-managed keys in the navigation pane and select a key. Look for Last used on the general configuration.
Figure 1: KMS key general configuration page
Choose the link under Last used to see additional details such as Timestamp, Operation, and the CloudTrail event ID.
Figure 2: View last used details including timestamp, operation, and event ID
The Last used column is also shown when you attempt to schedule key deletion, so that you can make informed decisions.
Figure 3: Scheduled key deletion warning
API reference
See the following examples for ideas on how to use the GetKeyLastUsage API to better understand KMS key usage.
Use case 1: Cost optimization through unused key cleanup
If you manage thousands of AWS KMS keys distributed across multiple AWS accounts, you might have keys that have remained unused since creation or keys that are no longer needed. By cleaning up these keys, you can reduce operational costs and minimize your security footprint. However, without visibility into which keys are actively performing cryptographic operations, it can be difficult to distinguish between keys protecting critical workloads and those that can be safely decommissioned.
Note that there are some precautions that you should take before scheduling key deletion. While the last usage information can help identify unused keys, it shouldn’t be the only factor in deciding whether to delete or disable a key. The last usage information tells you when a key was last used, not whether it will be needed in the future. A key might be unused for months but still required to decrypt files, for compliance scenarios or disaster recovery as shown in figure 4.
When you identify a potentially unused key, first disable it using DisableKey and monitor your applications and services for any encryption or decryption failures.
Figure 4: A use case where GetKeyLastUsage doesn’t accurately reflect whether a KMS key is still required
As an example, Amazon EBS volumes only interact with KMS keys during specific lifecycle events like volume creation, attachment, and detachment. After a volume is attached to an Amazon Elastic Compute Cloud (Amazon EC2) instance, the plaintext data encryption key is cached in the Nitro Card hardware, and all subsequent read/write operations use this cached key without any further AWS KMS API calls. This means a production volume running continuously for months or years will show no KMS activity during that entire period. However, the volume remains completely dependent on that KMS key for any future operations like instance restarts, volume reattachments, or disaster recovery scenarios. If someone deletes the KMS key, the encrypted data key stored with the volume can never be decrypted again, making the volume’s data permanently and irreversibly inaccessible. Before deleting any KMS key, you must verify it has no associated EBS volumes or snapshots, regardless of how long ago the last KMS API call occurred.
AWS provides a mechanism where you can create a CloudWatch alarm that notifies you if a key pending deletion is being accessed, giving you an opportunity to cancel the deletion before data becomes inaccessible.
Solution with GetKeyLastUsage API
Here’s a sample script that scans all customer-managed keys in an account and retrieves each key’s last usage date through the GetKeyLastUsage API. It accepts two optional inputs: a threshold in days and an AWS Region. The script filters and displays only keys that haven’t been used within the specified period, presenting results in a table with the key name, AWS account ID, AWS Region, and last usage date. This can help you identify unused encryption keys.
The following is an example to scan all keys that haven’t been used in the last 180 days in the us-east-1 Region:
./script.sh 180 us-east-1
#!/bin/bash
DAYS=${1:-90}
REGION=${2:-$(aws configure get region)}
CUTOFF=$(date -v-${DAYS}d +%s 2>/dev/null || date -d "-${DAYS} days" +%s)
ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)
printf "Showing keys not used in the last %s days (Region: %s)\n\n" "$DAYS" "$REGION"
printf "%-50s %-15s %-20s %-15s\n" "Key Name" "Account ID" "Region" "Last Usage Date"
printf "%.0s-" {1..100}
printf "\n"
for key_id in $(aws kms list-keys --region $REGION --query 'Keys[*].KeyId' --output text); do
key_manager=$(aws kms describe-key --region $REGION --key-id $key_id --query 'KeyMetadata.KeyManager' --output text)
if [ "$key_manager" = "CUSTOMER" ]; then
last_usage=$(aws kms get-key-last-usage --region $REGION --key-id $key_id)
timestamp=$(echo $last_usage | jq -r '.KeyLastUsage.TimeStamp // empty')
if [ -z "$timestamp" ]; then
last_epoch=0
else
last_epoch=$(date -jf "%Y-%m-%dT%H:%M:%S" "$(echo $timestamp | cut -d. -f1)" +%s 2>/dev/null || date -d "$timestamp" +%s)
fi
if [ "$last_epoch" -lt "$CUTOFF" ]; then
key_alias=$(aws kms list-aliases --region $REGION --key-id $key_id --query 'Aliases[0].AliasName' --output text)
key_name=${key_alias:-$key_id}
[ "$key_name" = "None" ] && key_name=$key_id
if [ -z "$timestamp" ]; then
tracking_date=$(echo $last_usage | jq -r '.TrackingStartDate' | cut -d'T' -f1)
last_used="${tracking_date}*"
else
last_used=$(echo $timestamp | cut -d'T' -f1)
fi
printf "%-50s %-15s %-20s %-15s\n" "$key_name" "$ACCOUNT_ID" "$REGION" "$last_used"
fi
fi
done
printf "\n* = No operations performed since tracking started\n"
Use case 2: Preventing accidental key deletion with policy controls
Organizations frequently face the risk of accidental key deletions, which can have severe operational consequences. Despite precautions and safety measures, accidents can happen. A key might be deleted because someone believes it’s no longer in use, only to discover that critical applications or workloads depend on it. This results in data access failures, application downtime, and emergency recovery procedures. Without visibility into recent key usage, teams lack the information needed to make safe disable decisions or implement effective safeguards.
Solution with policy based controls
To prevent KMS keys from being accidentally Disabled or Deleted use the kms:TrailingDaysWithoutKeyUsage condition key in key policies to automatically block deletion or disabling of recently used keys:
Open the AWS KMS console and choose Customer managed keys in the navigation pane.
Select the key you want to protect.
In the Key policy tab, choose Edit.
In the policy editor, add the following statement:
The policy prevents deletion or disabling a key if it was used within the past 365 days. You can adjust the threshold to match your organization’s requirements. For more information about the condition key, see kms:TrailingDaysWithoutKeyUsage.
Important considerations
When reviewing key usage for possible deletion, consider the following:
Key deletion is irreversible and makes encrypted data unrecoverable. AWS enforces a 7–30 day waiting period. During this time, monitor usage attempts and cancel the deletion if necessary. Delete a key only if you’re certain that no data has been encrypted or will be encrypted with it. Consider disabling the key first to test the impact of unavailable keys.
CloudTrail remains authoritative because it provides the full audit trail. GetKeyLastUsage quickly tells you when and what operations occurred, but CloudTrail shows you who made the request and with what parameters. Learn more about logging KMS API calls with CloudTrail.
Conclusion
The GetKeyLastUsage API enhances your KMS key management capabilities by providing immediate access to usage data that was previously only present in CloudTrail logs. Start by opening the AWS KMS console and checking the Last used field for any customer-managed keys and AWS managed keys to see this information in action. For broader key auditing, integrate the API into your existing automation scripts using the AWS CLI examples provided.
If you have feedback about this post, submit comments in the Comments section below.
Extracting actionable insights from thousands of contracts and legal documents remains a challenge. For organizations, critical business information is locked in unstructured documents such as contracts, legal agreements, provider arrangements, and vendor invoices. Extracting and operationalizing this information has traditionally been a manual, error-prone, and resource-intensive process. This leads to missed savings opportunities, costly delays, and significant inefficiencies across the enterprise.
AArete, a global management and technology consulting firm specializing in healthcare, recognized this challenge and developed Doczy.ai, an intelligent contract interpretation solution powered by generative AI on Amazon Web Services (AWS).
In this post, we show you how Doczy.ai uses generative AI on AWS to automate contract intelligence at scale, transforming unstructured documents into structured, actionable insights, so organizations can automate critical business processes and unlock the full value of their data.
The challenge: Data trapped in documents
For healthcare organizations, managing and interpreting contracts and documents represents a major operational bottleneck. Manual review processes require deploying teams to extract data from thousands of documents. This is an approach that is neither scalable nor sustainable, highly prone to error, and costly. Organizations relying on institutional knowledge face additional risks: critical information resides with a few key individuals, creating knowledge silos and succession planning challenges. Existing Contract Lifecycle Management (CLM) systems often prove inadequate for capturing the nuanced and complex terms unique to each agreement. These legacy systems can only configure predefined fields, missing the rich detail and contextual information that distinguishes contracts. The downstream impact is substantial: in healthcare, reimbursement terms must be manually translated into claims systems—a slow, error-prone process. Similarly, verifying vendor invoices against contract terms often requires manual effort, leading to payment processing delays and missed contractual savings opportunities. These inefficiencies ultimately leave significant value on the table.
This is where Doczy.ai provides significant value.
Doczy.ai: An intelligent contract interpretation solution
Doczy.ai directly addresses these challenges using advanced AI and scalability on AWS. Developed by AArete, Doczy.ai pushes the boundaries of document intelligence. The solution automatically interprets complex documents and converts them into a structured, queryable information repository that allows organizations to unlock the full value of their data and drive smarter decisions.The evolution of Doczy.ai reflects rapid AI advancement. Prior to 2020, document processing required manual effort, with individuals processing approximately 100 documents per week. Between 2020–2023, the firm implemented rules-based contract processing, achieving approximately 55% accuracy. The breakthrough came in 2024 with an AI-based processing built on AWS achieved 99% accuracy—a dramatic improvement over the 55% accuracy of traditional rules-based systems.
Doczy.ai architecture
Doczy.ai is built on a comprehensive AWS architecture designed to handle the entire document processing lifecycle: from the moment a file enters the system to the moment it generates actionable business intelligence.
Architecture of Doczy.ai
External users access the platform through a secure Next.js frontend, with Amazon Cognito managing authentication and authorization behind the scenes. After authentication, users upload documents directly to Amazon Simple Storage Service (Amazon S3), where durable, scalable object storage ensures nothing is lost and everything is accessible at scale. From there, the real intelligence begins.
An AWS Lambda function triggers Amazon Textract to extract text and metadata from documents in various formats. What sets Doczy.ai apart at this stage is its patented “smart chunking” algorithm, a proprietary approach that goes far beyond pulling words off a page. Rather than treating a document as a flat sequence of text, smart chunking preserves hierarchical structure and one-to-many relationships within documents. It uses a combination of semantic and keyword search to decompose text into meaningful, context-aware chunks, applying dynamic parameters to maintain logical relationships throughout. Sequential identifiers and metadata-driven grouping organize these chunks into field groups, detecting overlaps and removing duplications while keeping the document’s natural flow intact.
After chunking, the document enters the dual clustering engine of Doczy.ai. This two-lens methodology analyzes every contract simultaneously from both a semantic and a structural perspective. On the semantic side, extracted text is converted into embeddings, numerical representations of meaning, and similar ideas are grouped together even when they’re expressed in different words. On the structural side, pattern-recognition algorithms identify clause types, formatting conventions, table layouts, and hierarchical organization, understanding. For example, that a three-nested-level exhibit carries fundamentally different implications than a straightforward attached schedule.These two analyses don’t operate in isolation. Projection algorithms compare the semantic and structural clusters side by side, synthesizing them into a unified, enriched document model that captures both meaning and context. It’s this convergence that drives the 99% accuracy rate of Doczy.ai. The system doesn’t just read the words, it understands the contract. Advanced large language models (LLMs) then generate structured output grounded in this dual-clustered intelligence.Before output is finalized, the system determines each document’s file class and generates prompts tailored to the extracted text, cluster classification, and domain context. Through few-shot and multi-shot prompting, the platform continuously edits the prompt on domain-specific examples and based on real outputs, creating a feedback loop that compounds accuracy improvements over time.
The resulting structured data flows into Snowflake, forming a centralized repository that powers intelligent dashboards with actionable insights and visualizations. Throughout the entire pipeline, Amazon CloudWatch monitors performance in real time and proactively surfaces issues before they escalate, while AWS Secrets Manager safeguards sensitive information, ensuring that security is not an afterthought, but a foundational layer woven into every stage of the system.
The transformative impact of Doczy.ai
The results of this AI-powered approach are transformative and measurable. By automating contract interpretation and document processing, Doczy.ai has demonstrated significant impact at scale for multiple organizations across healthcare and financial services. The scale of operations over the last 22 months demonstrates the maturity and production readiness of Doczy.ai. This solution has processed 2.5 million contract documents (50 million pages) with 137 million API calls to Amazon Bedrock and 442 billion tokens—a level of automation and accuracy previously unattainable through manual or traditional document processing approaches. Over this same period, Doczy.ai has helped clients achieve approximately 330 million dollars in cumulative direct and indirect savings.The 99% accuracy rate represents significant improvement over the approximately 55% accuracy of rules-based systems and far exceeds manual processing, which is typically affected by fatigue and human error. The 97% reduction in manual processing time translates directly to cost savings and enables organizations to reallocate human resources to higher-value activities that require judgment and strategic thinking.
A use case in action: Business process automation for health plans
For health plans, Doczy.ai provides a powerful solution to automate and improve contract management across the entire lifecycle. It ingests existing contracts in both paper and digital formats, integrates with contract management systems such as Coupa and Icertis, and processes new contracts and amendments as they’re executed. It then creates a centralized metadata repository that feeds directly into downstream systems, enabling end-to-end business process automation.This automation unlocks critical capabilities: Organizations can continuously analyze and improve contract terms, identifying opportunities to improve financial performance and operational efficiency. The architecture feeds accurate, up-to-date contract data directly into claims systems, automating the configuration process that previously required manual translation of reimbursement terms and removing manual data entry, configuration errors, and delays. Additionally, the platform helps maintain claim payment accuracy by assessing payments against contract terms, identifying discrepancies, and flagging potential overpayments or underpayments before they occur.By automating manual processes, health plans can adapt quickly to new contract terms and regulatory requirements. The intelligent dashboards and actionable insights provided by Doczy.ai enable decision-makers to understand contract performance, identify trends, and take proactive action to optimize financial outcomes.
Getting started with Doczy.ai
Organizations interested in using Doczy.ai to transform document processing and contract management can engage with AArete to discuss their specific use cases and requirements. AArete offers the platform as a Software as a Service (SaaS) solution, enabling rapid deployment without significant infrastructure investment. AArete’s team of experts will configure this solution for your specific document types, domain terminology, and business processes, supporting maximum value from day one.
Conclusion
The challenge of unlocking data from unstructured documents is a major hurdle for many businesses, particularly in healthcare and financial services where contracts and agreements govern critical operational and financial relationships. By embracing intelligent document intelligence on AWS, organizations can solve this long-standing operational challenge and unlock a new frontier of strategic advantage, turning their data into their most valuable asset.
Built on a sophisticated architecture that orchestrates Amazon Cognito, Amazon S3, AWS Lambda, Amazon Textract, Amazon Elastic Container Service (Amazon ECS), Amazon Bedrock, Amazon CloudWatch, and AWS Secrets Manager, Doczy.ai demonstrates how modern cloud services can solve complex document-heavy business problems. Its advanced hybrid smart chunking, dual clustering, and prompt optimization techniques form the core of a patented contract intelligence engine.
Doczy.ai delivers tangible impact, processing up to 250,000 contract documents per week with 99% accuracy, reducing manual processing time by 97%, and helping clients unlock roughly 330 million dollars in cumulative savings over 22 months. By embracing this intelligent document processing, organizations can turn contracts into a strategic data asset, improving efficiency, accuracy, and profitability while freeing teams to focus on higher-value work.
To learn more about how AArete and Doczy.ai can help your organization transform document processing and unlock the value of your unstructured data, visit the AArete website.
Multi-Region Event-Driven Failover Architecture with Amazon EventBridge and Route 53
Event-driven architectures enable applications to respond to events in real-time, providing scalability and loose coupling between components. However, ensuring high availability across multiple AWS regions requires careful design of failover mechanisms. This post demonstrates how to build a resilient multi-region event-driven architecture using Amazon EventBridge, Amazon API Gateway, and Amazon Route 53 health-based failover.
Overview
Organizations building event-driven applications need to achieve high availability and disaster recovery capabilities. This architecture provides automatic failover between AWS regions while maintaining regional independence for event processing. The solution uses Amazon Route 53 health checks to monitor regional Amazon API Gateway endpoints and automatically routes traffic to healthy regions without manual intervention.
The architecture delivers several key benefits. Regional independence reduces latency by processing events in the same region where they originate. Amazon DynamoDB global tables provide automatic data replication across regions, ensuring data availability during regional failures. The solution provides robust failover capabilities while maintaining architectural simplicity.
Organizations with strict availability requirements can find this solution particularly valuable. All event processing remains within AWS regions, and failover occurs automatically based on health check results. The architecture supports both planned maintenance windows and unplanned regional outages, providing flexibility for operational needs.
Solution overview
The solution implements an active-passive multi-region architecture where events flow through Amazon API Gateway to regional Amazon EventBridge buses. Amazon Route 53 health checks monitor the primary region and automatically route traffic to the secondary region during failures. Each region processes events independently, while Amazon DynamoDB Global Tables replicate data across regions.
The following diagram provides an overview of the solution:
The above diagram depicts the multi-region architecture running across two AWS regions. The Route 53 DNS service serves as the main entry point for the application, with health checks monitoring both regions. Each region contains an identical stack with Amazon API Gateway, Amazon EventBridge, Amazon SQS, and AWS Lambda. The Amazon DynamoDB Global Table replicates data between regions automatically.
Solution deployment
To deploy this solution, follow the instructions in the GitHub repository and clone the repository. The solution deploys in two AWS regions. Ensure valid SSL certificates exist in AWS Certificate Manager (ACM) in both regions for the custom domain.
Prerequisites
For this walkthrough, the following resources are needed:
AWS Account: An AWS account with permissions to create and manage Amazon API Gateway, Amazon EventBridge, Amazon SQS, AWS Lambda, Amazon DynamoDB, Amazon Route 53, AWS IAM, and AWS CloudFormation resources
AWS Serverless Application Model (SAM): The AWS SAM CLI installed, as the templates use the SAM transform for Lambda and API Gateway resource definitions
Domain Name: A registered domain with a Route 53 hosted zone- SSL Certificates: ACM certificates for the custom domain in both deployment regions
AWS CLI: The AWS CLI installed and configured with credentials for the target AWS account
Region Selection: Two AWS regions for deployment
Walkthrough
The AWS CloudFormation templates from the sample GitHub repository create a secure, multi-region architecture that provides automatic failover for event-driven applications. The templates provision regional API Gateway endpoints, EventBridge buses, SQS queues, Lambda functions, and an Amazon DynamoDB Global Table. The solution establishes health monitoring through Route 53 health checks and configures DNS failover routing. The templates use AWS Serverless Application Model (SAM) transform to simplify Lambda and API Gateway resource definitions.
Step 1: Deploy the primary stack
The primary stack creates the foundational resources in the primary region. This includes the Amazon EventBridge bus, Amazon API Gateway with custom domain, health check, AWS Lambda function, Amazon SQS queue, and Amazon DynamoDB Global Table. The stack creates an EventBridge bus that receives events from API Gateway:
Note the `DataTableName` output value for use in the secondary stack deployment. The `CustomDomainURL` output provides the endpoint to invoke the solution.
Step 2: Deploy the secondary stack
The secondary stack creates identical resources in the secondary region , except for the Amazon DynamoDB table which references the existing Global Table. The secondary stack creates its own Amazon EventBridge bus, Amazon API Gateway, health check, AWS Lambda function, and Amazon SQS queue. The Route 53 DNS record uses the SECONDARY designation
Step 3: Event processing flow
Events flow through the processing pipeline in each region. API Gateway receives events and forwards them to EventBridge using the PutEvents API. EventBridge evaluates event rules and routes matching events to SQS queues. Lambda functions poll the SQS queues and process events in batches. AWS Lambda writes processed data to the DynamoDB Global Table, which replicates across regions.
The Lambda function processes events from the queue and writes to DynamoDB:
def handler(event, context):
for record in event.get('Records', []):
body = json.loads(record['body'])
detail = body.get('detail', {})
event_id = body.get('id', '')
item = { 'id': event_id, 'detail': detail, 'timestamp': datetime.utcnow().isoformat() }
table.put_item(Item=item)
Testing
Fetch the custom domain URL and test it by sending an event:
Wait 2-3 minutes for the health check to fail. The Route 53 health check performs checks every 30 seconds with a failure threshold of 3, requiring 90 seconds to detect the failure.
You can find the “deployment-id” by running: aws apigateway get-deployments \ --rest-api-id <primary-api-id> \ --region {primary region}
After 2-3 minutes, the health check passes and Route 53 routes traffic back to the primary region.
Cleanup
To remove the solution and avoid ongoing charges, delete the CloudFormation stacks in the correct order. Delete the secondary stack first, then the primary stack. This order is important because the Amazon DynamoDB Global Table is owned by the primary stack. Warning: Deleting these stacks permanently removes all resources including the Amazon DynamoDB global table and any event data stored in it. Back up any data you need before proceeding. This action cannot be undone. The following resources incur costs while deployed:
Amazon API Gateway (REST API)
Amazon Route 53 health checks and DNS records
Amazon DynamoDB global table (with cross-region replication)
This removes all resources including the Amazon EventBridge buses, Amazon API Gateways, AWS Lambda functions, Amazon SQS queues, Amazon DynamoDB Global Table, Amazon Route 53 health checks, DNS records and IAM roles.
Conclusion
This post demonstrates how to establish a resilient multi-region architecture for event-driven applications using Amazon EventBridge, Amazon API Gateway, and Amazon Route 53. The solution uses Route 53 health-based failover, a powerful capability that automatically routes traffic to healthy regions based on health check results. This architecture significantly enhances application availability by providing automatic failover during regional outages while maintaining regional independence for event processing.
Imagine a teammate who needs to find a user across thousands of accounts with only a partial email address, a last name, and a known access level. How quickly can your team respond? If your use case involves straightforward searches on standard Amazon Cognito attributes, the built-in ListUsers API is likely all you need. But for advanced scenarios involving custom attributes, fuzzy matching, complex filtering, and sub-second response times, a dedicated search layer is the right investment.
Amazon Cognito provides robust user authentication and management capabilities for modern applications. As applications scale, development teams typically implement advanced search functionality to find users by partial email match, segment group membership, or audit across multiple custom attributes.
This solution extends Amazon Cognito with advanced search capabilities using AWS Lambda, Amazon DynamoDB, and Amazon OpenSearch Serverless.
Key capabilities:
Multiple search types: Exact match, prefix match, and fuzzy search
Complex filtering: Query across email, phone, groups, and registration date simultaneously
High performance: Sub-second response times at any scale
Automatic synchronization: Real-time updates as users authenticate or update profiles
API-driven: RESTful API with pagination support
The architecture uses Cognito Lambda triggers to capture user data during authentication, stores it in DynamoDB, and indexes it in OpenSearch Serverless through DynamoDB Streams. The following architecture diagram illustrates how these components work together.
Figure 1: Solution architecture for Searchable Cognito Users
Walkthrough
The solution architecture demonstrates two flows: Ingestion flow and Search flow.
Ingestion flow
The ingestion flow captures and indexes user data through two paths: Cognito Lambda triggers and AWS CloudTrail. Together, these paths maintain synchronization between the search index and Cognito without requiring manual intervention or scheduled batch jobs.
1. Cognito Lambda triggers
This path captures user data during authentication events using a Cognito trigger Lambda function that handles two trigger types: Post-confirmation and Pre-token generation. The post-confirmation trigger creates the initial user record on sign-up, while the pre-token generation trigger tracks login activity and app client information on each subsequent authentication. The pre-token generation trigger also provides access to the user’s group membership in the event payload, which is indexed as a searchable field. The flow operates through the following steps:
Client initiates sign-up or login — User submits authentication request to Amazon Cognito.
Post-confirmation trigger — On sign-up, Cognito invokes the Cognito trigger Lambda which creates the initial user record in the DynamoDB user table with profile attributes (email, name, groups).
Pre-token generation trigger — On each login, Cognito invokes the Cognito trigger Lambda which updates the user’s login timestamp and app client information in the DynamoDB user table.
Stream processing — DynamoDB Streams detects the new or updated record and triggers the OSS ingest Lambda.
Index updated — OSS ingest Lambda processes the stream event and indexes the user data in OpenSearch Serverless.
Note: The Cognito Lambda triggers are deployed in a VPC. Cognito enforces a 5-second timeout on trigger functions. If you’re extending these triggers with additional functionality or already using post-confirmation or pre-token generation triggers, ensure the combined execution time stays well within this limit. Consider provisioned concurrency if cold starts are a concern.
Figure 2: User Data Ingestion via Cognito Lambda Triggers
2. CloudTrail
This path captures admin-initiated user changes that occur outside the authentication flow, such as creating users using the Cognito console or CLI. These actions don’t trigger Cognito Lambda triggers, so CloudTrail and EventBridge bridge the gap. The flow operates through the following steps:
Admin action performed — User performs an admin action in Amazon Cognito (for example, create user, update attributes, add to group, disable user).
API call logged — AWS CloudTrail captures the Cognito admin API call.
EventBridge rule matched — An Amazon EventBridge rule matches the Cognito admin event.
CloudTrail event Lambda invoked — EventBridge invokes the CloudTrail event consumption Lambda, which reads the current user state from Cognito and upserts the profile in the DynamoDB user table.
Stream change event — DynamoDB Streams emits the change event.
Invoke OSS Lambda — The stream event triggers the OSS ingest Lambda.
Index user data — OSS ingest Lambda indexes the updated user data in OpenSearch Serverless.
Figure 3: User Data Ingestion via CloudTrail
Figure 4: Data model for indexed user attributes in Amazon DynamoDB
Search flow
With the search flow, authorized users can query the indexed user directory:
Query submission — Authenticated user submits search query through the UI.
Request validation — API Gateway receives the request with the Cognito JWT token and validates it using the Cognito authorizer.
Search execution — Upon successful validation, the search Lambda function is invoked with the search parameters.
OpenSearch query — Lambda assumes a read-only role for OpenSearch Service access and executes the query against the OpenSearch Serverless index.
Results returned — Lambda formats and returns the query results to the frontend, where the UI displays them in a paginated format.
Figure 5: Search Flow Sequence Diagram
Figure 6: Demo UI user search integration on multiple properties
Figure 7: Demo UI user search integration on auto-suggest
Try it yourself
Ready to see this solution in action? The repository includes everything you need to deploy a complete working implementation in your own AWS environment.
The repository includes everything you need: AWS CDK infrastructure code, Lambda function implementations, a React frontend, and documentation. You can have a fully functional searchable user directory running in your account in under 20 minutes. When you’re finished testing, clean up all resources to avoid ongoing charges.
Conclusion
In this post, you learned how to extend Amazon Cognito with advanced search capabilities. By combining OpenSearch Serverless, DynamoDB Streams, and Lambda functions, you can build a scalable, event-driven architecture that automatically maintains a searchable user directory with sub-second query performance.
This pattern unlocks powerful use cases: support teams can quickly locate users across thousands of accounts, administrators can segment users by group membership for targeted communications, and compliance teams can audit user attributes with complex filtering.
To dive deeper into the AWS services powering this solution:
Network administrators face a persistent challenge: maintaining domain blocklists and allowlists that keep pace with the internet. New websites and services emerge daily, and keeping these lists current requires constant manual updates that leave gaps in coverage. This challenge intensifies when managing access to rapidly evolving categories like AI services, where new tools launch on a regular basis.
AWS Network Firewall is a managed, stateful network firewall and intrusion detection and prevention service for fine-grained control of your virtual private cloud (VPC) network traffic. With URL and domain category filtering, security teams can use predefined categories to control access instead of managing individual domains. AWS-managed URL and domain categories stay current automatically as new domains are registered, removing the need for manual list maintenance.
This feature is especially useful for organizations navigating AI governance. Instead of manually tracking every new AI service, you can control access to the entire Artificial Intelligence and Machine Learning category while creating exceptions for approved services. The same approach works for social media, streaming sites, gambling, and dozens of other categories, all with built-in audit trails for compliance reporting.
In this post, we walk through URL and domain category filtering configurations for AWS Network Firewall, from basic rules to exception handling and monitoring strategies that give you visibility into how your workloads interact with external services.
Streamlined policy management with predefined categories
With URL and domain category filtering, you control website access using predefined categories instead of individually specifying sites in a domain list rule group. You can select from AWS-managed categories such as Social Networking, Gambling, or Artificial Intelligence and Machine Learning to implement and maintain filtering policies. AWS keeps these categories current automatically, so you don’t need to update firewall policies when new domains are registered.
Network Firewall offers two category filtering options. Domain category filters by domain name using the TLS Server Name Indication (SNI) field, with no decryption required. URL category filters by the full URL path, which requires TLS inspection for HTTPS traffic. To keep things straightforward, this post focuses on domain category filtering. To set up URL category filtering with TLS inspection, see Creating a TLS inspection configuration in Network Firewall.
Prerequisites
To follow the steps in this post, start by making sure that you have the following prerequisites in place:
An existing Network Firewall deployment: This walkthrough assumes you have an existing Network Firewall deployment to filter egress traffic flows from your Amazon Virtual Private Cloud (Amazon VPC) in place. If you aren’t already using Network Firewall, see Getting started with AWS Network Firewall to set up your firewall before proceeding.
The HOME_NET variable set correctly at the firewall policy level: The rules in this post use the $HOME_NET variable to scope traffic to your internal network. In the AWS Management Console for Amazon VPC, select your firewall policy under the Firewall policies tab, select the Details tab, and check the policy variables section under HOME_NET variable override values. We recommend setting this to all RFC 1918 private IP address ranges: 10.0.0.0/8, 172.16.0.0/12, and 192.168.0.0/16. When you set $HOME_NET at the policy level, all rule groups associated with that policy inherit the value automatically. Network Firewall automatically maps $EXTERNAL_NET to the inverse of $HOME_NET, so configuring HOME_NET correctly also configures $EXTERNAL_NET.
Figure 1: Firewall policy details tab showing the HOME_NET variable override values set to RFC 1918 private IP address ranges
Create a category rule using the console rule builder
To get started quickly, you can create a domain category rule using the console’s built-in rule builder. In this example, we create a single alert rule for the Artificial Intelligence and Machine Learning category.
In the left navigation, scroll to Network Firewall and select Rule groups.
Choose Create rule group.
For Rule group type, select Stateful rule group.
For Rule group format, select Standard stateful rules.
For Rule evaluation order, select Strict order. Choose Next.
Figure 2: Create Network Firewall rule group page showing Stateful rule group type, Standard stateful rules format, and Strict order evaluation selected
Enter Domain-Category-Rules for the Name, Domain Category Rules for the Description, and 50 for the Capacity. Choose Next.
In the rule group editor, select the Category Matching radio button.
Under Category Matching, select Match all selected categories.
Under AWS category type, select Domain Category from the dropdown.
Under Categories, select Artificial Intelligence and Machine Learning.
For Protocol, select TLS.
For Source, select Custom, then enter $HOME_NET in the dialog box.
Set the Destination IP to Any.
For Action, select Alert.
Choose Add rule to add this rule to the rule group. Choose Next.
Figure 3: Completed category matching rule showing TLS protocol, $HOME_NET source, Any destination, and Alert action added to the rule group
Under Customer managed key, leave the default setting (Customize encryption settings should remain unchecked).
Under Add tags – optional, leave the default setting of no tags.
Choose Next, then Create rule group.
This rule generates an alert log entry each time a connection matches a domain in the Artificial Intelligence and Machine Learning category. It doesn’t block traffic. To block traffic, change the action to Drop or Reject in step 15.
Creating the same rule using Suricata compatible rule strings
The following walkthrough creates the same alert rule you built with the console rule builder, this time using a Suricata rule string.
In the Amazon VPC console, navigate to Network Firewall, then select Network Firewall rule groups.
Choose Create rule group.
For Rule group type, select Stateful rule group.
For Rule group format, select Suricata compatible rule string.
For Rule evaluation order, select Strict order. Choose Next.
Figure 4: Create Network Firewall rule group page showing Stateful rule group type, Suricata compatible rule string format, and Strict order evaluation selected
Enter Suricata-Domain-Category-Rules for the Name, Suricata Domain Category Rules for the Description, and 50 for the Capacity. Choose Next.
Leave the Rule variables section empty. The $HOME_NET variable is inherited from the firewall policy, as configured in the prerequisites.
Leave IP set references empty.
Paste the following rule into the Suricata compatible rule string editor:
alert tls $HOME_NET any -> $EXTERNAL_NET any (msg:"Artificial Intelligence and Machine Learning Category"; aws_domain_category:Artificial Intelligence and Machine Learning; sid:1000001;)
Choose Next.
Figure 5: Suricata compatible rule string editor with the domain category alert rule pasted in and the rule variables section left empty
Under Customer managed key, leave the default setting (Customize encryption settings should remain unchecked).
Under Add tags – optional, leave the default setting of no tags. Choose Next.
Choose Create rule group.
After creating the rule group, return to your firewall policy and add it under Stateful rule groups. We recommend associating new rule groups in a development or test environment first to validate behavior before deploying to production.
The following table explains each component of this rule:
alert
Action: generate an alert log entry when the rule matches. Other actions include pass, drop, and reject.
tls
Protocol: inspect TLS traffic, matching against the SNI field in the TLS Client Hello.
$HOME_NET any -> $EXTERNAL_NET any
Source and destination: match traffic from any internal IP address (HOME_NET) and port to any external IP address (EXTERNAL_NET) and port. The HOME_NET variable defines your internal network ranges, and the EXTERNAL_NET variable is automatically set to the inverse.
msg:”Artificial Intelligence and Machine Learning Category”
The message written to the alert log when this rule is triggered.
aws_domain_category:Artificial Intelligence and Machine Learning
The AWS-managed domain category to match against. The firewall looks up the destination domain in the category database and matches if the domain belongs to this category.
sid:1000001
A unique signature ID for this rule. Each rule in a rule group must have a unique SID.
Managing exceptions for approved services
You can manage exceptions to keep business-critical websites accessible. For example, say you need to allow access to OpenAI while blocking all other AI and ML traffic. To do this, return to the Suricata-Domain-Category-Rules rule group you created earlier and replace the basic alert rule with the following ruleset. Select the Suricata-Domain-Category-Rules rule group, under the Rules section, choose Edit.
Figure 6: Selecting Suricata-Domain-Category-Rules rule group to edit with new rules
Paste in the following rules and choose Save rule group.
# Allow OpenAI (TLS)
pass tls $HOME_NET any -> $EXTERNAL_NET any (tls.sni; dotprefix; content:".openai.com"; nocase; endswith; flow:to_server; alert; msg:"Allow OpenAI over TLS"; sid:1000001;)

# Allow OpenAI (HTTP)
pass http $HOME_NET any -> $EXTERNAL_NET any (http.host; dotprefix; content:".openai.com"; nocase; endswith; flow:to_server; alert; msg:"Allow OpenAI over HTTP"; sid:1000002;)

# Block all other AI/ML category traffic (TLS)
reject tls $HOME_NET any -> $EXTERNAL_NET any (msg:"Block non-approved AI/ML sites over TLS"; aws_domain_category:Artificial Intelligence and Machine Learning; flow:to_server; alert; sid:1000003;)

# Block all other AI/ML category traffic (HTTP)
reject http $HOME_NET any -> $EXTERNAL_NET any (msg:"Block non-approved AI/ML sites over HTTP"; aws_url_category:Artificial Intelligence and Machine Learning; flow:to_server; alert; sid:1000004;)
Figure 7: Suricata compatible rule string editor with the exception-based ruleset containing pass rules for OpenAI and reject rules for the AI/ML category
With strict order evaluation, the firewall evaluates rules in the order you define them. The pass rules for OpenAI appear first, so matching traffic is allowed before the broader category block rules run.
To verify the rules are working as expected, test from a host that routes traffic through your network firewall. These commands suppress the response body and check the exit code of the curl request. If curl completes a TCP connection, it prints CONNECTION ALLOWED. If the firewall resets the connection, curl exits with a non-zero code and prints CONNECTION BLOCKED.
A request to openai.com should succeed because it matches the pass rule:
When you add a domain category rule to your firewall policy, Network Firewall performs a category lookup for every connection that matches the rule’s protocol and IP specifications. The rules in this post match on $HOME_NET any -> $EXTERNAL_NET any, which means the firewall looks up the category for all outbound traffic originating from your internal network. This is why it’s important to have the $HOME_NET variable configured correctly at the firewall policy level. With this configuration, a single category rule is enough for category metadata to appear in your firewall logs across all matching connections, not just connections that match the specific category in your rule.
Each log entry includes an aws_category field containing a JSON array of all categories the destination domain belongs to. A single domain can map to multiple categories. For example, a request to chat.mistral.ai produces a log entry with “aws_category": "[\"Social Networking\",\"Artificial Intelligence and Machine Learning\"]” because that domain belongs to both categories.
The following sample log entry shows what a blocked request to chat.mistral.ai looks like using the exception-based rules from the previous section. The alert.signature field contains the rule’s msg value, and the aws_category field lists all categories the destination domain belongs to:
The aws_category field shows the domain belongs to both the “Social Networking” and “Artificial Intelligence and Machine Learning” categories. The verdict field confirms the connection was dropped with a TCP reset sent to the client.
Traffic that matches a pass rule with the alert keyword also generates a log entry with the aws_category field populated. For example, a connection to chat.openai.com that matches the OpenAI exception rule from the earlier section produces a log entry with alert.action set to “allowed” and the same category metadata. This means your queries capture both blocked and allowed traffic.
Querying logs with CloudWatch Logs Insights
If you send your firewall logs to Amazon CloudWatch Logs, you can use CloudWatch Logs Insights to analyze category traffic patterns. A single connection can generate multiple log entries (for example, a reject rule log and a default action log for the same flow), so the following queries deduplicate by flow_id to count each connection only once. Because a single domain can belong to multiple categories, results are grouped by category combination. For example, traffic to a domain categorized as both “Social Networking” and “Artificial Intelligence and Machine Learning” appears as a single combined entry.
To get started, navigate to the CloudWatch console. In the left navigation pane under Logs, select Logs Insights. Under Query scope, leave Log group name selected, then select your AWS Network Firewall alert logs log group. For the time window, we recommend starting with the default of 1 hour to keep the queries light. Enter each of the following queries into the editor and choose Run query to review the results. Note that CloudWatch Logs Insights queries incur charges based on the amount of data scanned. See Amazon CloudWatch pricing for details.
Most accessed categories
This query shows which category combinations your workloads connect to most frequently:
fields @timestamp, event.aws_category, event.flow_id
| filter ispresent(event.aws_category) and event.aws_category != "[]"
| stats latest(event.aws_category) as categories by event.flow_id
| stats count(*) as connections by categories
| sort connections desc
| limit 20
Figure 8: CloudWatch Logs Insights query results showing the most frequently accessed category combinations sorted by connection count
Least accessed categories
This query reverses the sort order to surface category combinations with the fewest connections, helping you identify categories that might not be relevant to your environment or that warrant further investigation:
fields @timestamp, event.aws_category, event.flow_id
| filter ispresent(event.aws_category) and event.aws_category != "[]"
| stats latest(event.aws_category) as categories by event.flow_id
| stats count(*) as connections by categories
| sort connections asc
| limit 20
Figure 9: CloudWatch Logs Insights query results showing the least frequently accessed category combinations sorted by connection count ascending
Most accessed categories, allowed traffic only
The event.verdict.action field indicates the actual outcome of each connection:drop for blocked traffic and alert for allowed traffic. This query shows which category combinations have the most allowed connections:
fields @timestamp, event.aws_category, event.flow_id, event.verdict.action
| filter ispresent(event.aws_category) and event.aws_category != "[]"
| stats latest(event.aws_category) as categories, latest(event.verdict.action) as verdict by event.flow_id
| filter verdict = "alert"
| stats count(*) as connections by categories
| sort connections desc
| limit 20
Figure 10: CloudWatch Logs Insights query results showing the most accessed category combinations filtered to allowed traffic only
Most accessed categories, blocked traffic only
The same query filtered to blocked connections. Change the verdict filter to drop:
fields @timestamp, event.aws_category, event.flow_id, event.verdict.action
| filter ispresent(event.aws_category) and event.aws_category != "[]"
| stats latest(event.aws_category) as categories, latest(event.verdict.action) as verdict by event.flow_id
| filter verdict = "drop"
| stats count(*) as connections by categories
| sort connections desc
| limit 20
Figure 11: CloudWatch Logs Insights query results showing the most accessed category combinations filtered to blocked traffic only
Drill down into a specific category
This query uses a like filter to find all traffic where the aws_category field contains a specific category, regardless of what other categories the domain also belongs to. In this example, the query returns all domains your workloads have connected to that map to the Artificial Intelligence and Machine Learning category, broken down by domain and verdict. Replace the category name in the like filter to investigate any category.
fields @timestamp, event.tls.sni, event.aws_category, event.verdict.action, event.flow_id
| filter ispresent(event.aws_category) and event.aws_category like /Artificial Intelligence and Machine Learning/
| stats latest(event.tls.sni) as sni, latest(event.verdict.action) as verdict by event.flow_id
| stats count(*) as connections by sni, verdict
| sort connections desc
| limit 20
Figure 12: CloudWatch Logs Insights query results showing a drill down into the Artificial Intelligence and Machine Learning category with connections broken down by domain and verdict
Bandwidth consumption by category
This query shows which category combinations consume the most egress bandwidth. It correlates flow logs (which contain byte counts) with alert logs (which contain category data) using the shared flow_id field. To run this query, select both your alert log group and your flow log group in CloudWatch Logs Insights.
fields @timestamp
| filter ispresent(event.netflow.bytes) or ispresent(event.aws_category)
| stats sum(event.netflow.bytes) as flowBytes, latest(event.aws_category) as categories by event.flow_id
| filter ispresent(categories) and categories != "[]"
| stats sum(flowBytes) as totalBytes by categories
| sort totalBytes desc
| limit 20
Figure 13: CloudWatch Logs Insights query results showing bandwidth consumption by category combination sorted by total bytes descending
These queries help you identify which categories your workloads access by volume, surface blocked and allowed traffic patterns, and pinpoint where the bulk of your egress bandwidth is going.
Conclusion
In this post, you walked through how to set up URL and domain category filtering on AWS Network Firewall, from creating your first category rule using both the console rule builder and Suricata compatible rule strings, to managing exceptions for approved services and monitoring category traffic patterns with CloudWatch Logs Insights. With AWS-managed categories that stay current automatically, you can control access to broad classes of websites without maintaining individual domain lists, and the built-in aws_category log field gives you the visibility to track how your workloads interact with external services.
This feature is available in all AWS commercial regions where AWS Network Firewall is supported.
Zynga, a global leader in interactive entertainment operates a portfolio of mobile game studios including Socialpoint, the creators of Dragon City and Monster Legends. Zynga’s analytics platform processes telemetry and revenue data across studios using Amazon Redshift as its central data warehouse.
As Zynga expanded its analytics architecture to include individual studios with their own compute environments, the team faced a challenge: how to maintain centralized data governance while granting studios independent query capacity. Their existing approach to permission management introduced lag and required custom infrastructure if scaled to multiple warehouses.
In this post, we walk through how Zynga adopted Amazon Redshift federated permissions and AWS IAM Identity Center to enforce consistent, tiered data access across provisioned and serverless Amazon Redshift environments without building custom synchronization pipelines.
The challenge
Zynga needed to onboard Socialpoint’s current Amazon Redshift workloads and make Zynga’s central data available to them. Zynga’s existing production cluster would house the Socialpoint raw data, but the compute would come from another warehouse set up as a consumer. At the same time, Zynga’s data access control policies would need to be enforced across all warehouses. Zynga uses a tiered access control policy which would need to be synced across all consumers with no permission lag or manual grant synchronization.
During the migration, Socialpoint’s specific extract, transform, and load (ETL) processes would be included in Zynga’s central ETLs and their data ingestion pipeline would be replaced by Zynga’s latest generation of data ingestion infrastructure. Because the migration process happens in stages, Amazon Redshift sizing would also gradually need to increase.
The team evaluated two alternatives before arriving at a solution:
Manual grants on consumer clusters introduced a delay between when permissions were updated on the producer and when they took effect on the consumer. This approach would also require an external job that synced permissions and would be unlikely to scale well beyond 2–3 consumers.
Solution overview
Zynga implemented a solution using three AWS services working together:
Amazon Redshift federated permissions enabled cross-cluster queries without explicit data shares. Permissions granted on the producer cluster propagate immediately to consumer workgroups through AWS Glue Data Catalog registration.
AWS IAM Identity Center provides unified authentication through federation with Okta. When users sign in, their Okta group memberships are provisioned through a System for Cross-domain Identity Management (SCIM) and automatically map to Amazon Redshift roles, removing the need for external synchronization jobs.
Amazon Redshift Serverless provides the compute layer for Socialpoint, scaling to zero when idle and avoiding the need to pre-size a provisioned cluster during the migration period.
The architecture uses a dual-grant approach where every permission is granted to both an IAM Identity Center group (for users) and a federated IAM role (for service accounts). This gives both authentication paths the same access.
How it works
Authentication with IAM Identity Center
Zynga’s existing Okta directory syncs to IAM Identity Center, which is connected to the Amazon Redshift Serverless workgroup. When a user authenticates, Amazon Redshift automatically creates a user mapped to their email address and assigns them to roles based on their Okta group membership.
For example, an analyst in the Gamma Tier group signs in and is automatically assigned the AWSIDC:role.sso.gamma role in Amazon Redshift. No manual role assignment or synchronization job is required.
Service accounts, used for programmatic access, authenticate differently. Either using their IAM role and calling the get-credentials API, or by using the new federated permissions feature. Each service account assumes a federated IAM role, which creates a corresponding federated user in Amazon Redshift (for example, IAMR:role_iam_gamma).
Figure 1 – Identity layer
The dual-grant approach
To ensure that both users and service accounts can access the same data, every read permission is granted to both the IAM Identity Center group and the federated IAM role in a single statement:
GRANT SELECT ON schema.table TO
	'IAMR:role_iam_gamma',
	ROLE 'AWSIDC:role.sso.gamma';
Transitioning the producer cluster
The shared provisioned cluster already had active users with local grants. To avoid disruption, Zynga implemented a tri-grant approach on the producer during the transition period. Existing stored procedures were modified to grant permissions to three targets: the legacy local role, the IAM Identity Center group, and the federated IAM role.
GRANT SELECT ON schema.table TO
	ROLE role_rs_gamma,
	ROLE 'AWSIDC:role.sso.gamma','IAMR:role_iam_gamma';
This approach maintains backward compatibility for existing users on the producer while enabling immediate access from the new serverless workgroup. The long-term plan includes migration of all producer users to IAM Identity Center and retire the legacy local grants.
Stored procedures for consistent governance
Rather than requiring users to construct dual-grant statements manually, Zynga created stored procedures that encapsulate the grant logic:
grant_read accepts a table name and access tier, then issues the appropriate dual-grant for both the IAM Identity Center group and the federated IAM role.
grant_write grants data definition language (DDL) and data manipulation language (DML) permissions to the appropriate team-based role.
This provides a consistent interface for permission management regardless of which cluster or workgroup that the user is on.
Figure 2 – Data and compute layer
Results
The migration delivered measurable improvements:
Immediate permission propagation – Grants on the producer cluster took effect on the consumer workgroup instantly, replacing a process that previously required manual intervention and introduced lag.
Zero additional infrastructure cost – Federated permissions, federated queries, and IAM Identity Center added no incremental costs to the architecture.
Removed custom synchronization – The team removed the need for Lake Formation configurations, external AWS Lambda functions, and Airflow workflows for permission management.
Scalable pattern – The same architecture can be extended to additional studio workgroups without duplicating permission management logic.
Lessons learned
Zynga adopted federated permissions shortly after the feature launched in US West Oregon (us-west-2) in January 2026. The team shared several observations from their early adoption:
Run a proof of concept first. The team validated the full permission model in a test environment before deploying to production, including testing that existing data shares to other clusters were not disrupted.
Plan for the dual-grant requirement. Because IAM Identity Center users and federated IAM roles are distinct identity types, every read permission requires two grants. Encapsulating this in stored procedures prevents errors and reduces cognitive overhead.
Start with serverless for new workloads. With Amazon Redshift Serverless, the team can avoid sizing decisions during the migration period. If usage patterns later justify it, they can migrate to a provisioned cluster from a serverless snapshot with minimal downtime.
Engage with AWS. As an early adopter of a new feature, Zynga maintained regular contact with the Amazon Redshift team through their AWS Technical Account Manager to report issues and request enhancements.
Conclusion
Zynga’s adoption of Amazon Redshift federated permissions demonstrates how organizations with multi-cluster Amazon Redshift architectures can enforce centralized data governance without building custom synchronization infrastructure. By combining federated permissions with IAM Identity Center and Amazon Redshift Serverless, the team established a pattern that scales to additional studios while maintaining consistent access controls and reducing operational overhead.
To learn more about the services used in this post, see the following resources:
Managing sensitive data across sprawling data environments is hard. In this post, we show you how to tackle data discovery, classification, and governance across your databases, data warehouses, and object storage to regain visibility and control over your data landscape. As you build new features, products, and services, your data naturally spreads across multiple systems to meet immediate application and business needs. Different teams spin up their own data stores, and before long, you’re dealing with a complex web of repositories—often with limited visibility into what exists where. This data sprawl becomes most challenging when you must understand and protect your sensitive data. Security teams often struggle to maintain accurate inventories of data categorization and classification. Stakeholders demand comprehensive insights into data classification and processing activities, usually on tight deadlines, and keeping up-to-date data inventories becomes increasingly daunting as your data grows. Without automation, you’re left with manual processes that stretch over weeks, leave room for human error, and create unnecessary business risk.
The need for automation
In a typical manual scenario, creating a new database triggers a chain of time-consuming events. The governance team reviews the new data source, documents its contents, and scans for sensitive data. The security team assesses its configuration and access controls. Days or weeks pass before you fully understand this new asset’s sensitivity.
With automation, creating a new database triggers immediate action. The system detects the new source, catalogs its structure, identifies sensitive data, and updates a central inventory within minutes, supporting proper governance from the moment you create it. Here’s how it works on AWS: When you create an Amazon Simple Storage Service (Amazon S3) bucket for customer orders, you add tags such as Business Function, Data Owner, and Purpose. After the bucket is in use, the system detects it, creates catalog entries, analyzes data patterns, identifies sensitive information, and updates governance records without additional input from you. This gives your organization real-time visibility. Security teams instantly see which repositories contain sensitive information. Governance teams generate up-to-date inventory reports on demand, and data teams immediately understand sensitivity levels, helping them use data responsibly.
Solution overview
The solution uses key AWS services across three layers that work together for comprehensive data visibility and categorization.
Detection Layer: Continuously monitors your AWS environment for new resource creation. When you provision an Amazon S3 bucket, Amazon Relational Database Service (Amazon RDS) database, or Amazon DynamoDB table, Amazon EventBridge rules capture this activity and initiates the governance workflow, so no data source goes unnoticed.
Figure 1 Automated data source discovery (S3 example) workflow using EventBridge Rules and Lambda functions
Processing Layer: After a new source is detected, AWS Glue crawlers analyze its schema while specialized jobs scan for sensitive data patterns. The system also extracts metadata from resource tags, enriching your understanding of each repository’s purpose and ownership.
Figure 2 PII detection and processing workflow using AWS Glue jobs and DynamoDB staging
Management Layer: Maintains a central source of truth about your data assets. AWS Glue Data Catalog provides a unified view across your organization, tracking schema changes and sensitivity levels. This layer also manages the processing workflow state and generates insights for stakeholders.
Figure 3 Tag-based metadata capture and Data Catalog update workflow
Setting up the solution
This solution uses AWS Cloud Development Kit (AWS CDK) for deployment, organized into four stacks that build upon each other.PrerequisitesBefore deployment, verify that you have:
Access to an AWS account with permissions to create resources in Amazon S3, AWS Lambda, Amazon DynamoDB, AWS Glue, and Amazon EventBridge
Node.js (version 18 or later) and npm installed
Access to a terminal to run AWS CDK CLI commands
Basic familiarity with AWS Console navigation
Step 1: Infrastructure deployment
Deploy four stacks using AWS CDK. Each establishes components for data discovery, cataloging, and PII detection.
BaseInfraStack: Deploys core infrastructure—Amazon Virtual Private Cloud (Amazon VPC), DynamoDB tables for state management, EventBridge rules for monitoring, and Lambda functions for orchestration.
GlueAssetsStack: Sets up S3 buckets for AWS Glue ETL scripts and deploys PySpark code for PII detection.
GlueJobCreationStack: Creates Data Catalog databases and deploys Lambda functions that automate the creation of AWS Glue crawlers and PII detection jobs for newly discovered data sources.
ReportingStack: Deploys Lambda functions that process PII detection results and tag metadata, updating the Data Catalog accordingly.
To deploy these stacks, you will use the AWS CDK CLI, running the following commands:
In the AWS Management Console, open DynamoDB and find the glueJobTracker table. This table is a critical component of the framework:
Purpose: Central state management – tracks processing states and configurations for discovered data sources.
Current state: The table should be empty because no discovery processes have been triggered yet.
Structure: Tracks states such as Data Catalog entry creation and PII detection job setup for each data source.
By verifying this table, you confirm that the infrastructure is ready to begin tracking new data sources.
Figure 5 Empty DynamoDB glueJobTracker table before execution
Solution in action
This solution runs automatically in production through EventBridge triggers and scheduled AWS Glue crawlers. The following walkthrough executes each step manually so you can observe the workflow.You follow the journey of a newly created S3 bucket containing sensitive data, seeing how the solution discovers, catalog, and processes it through each stage.
Step 3: Create a new S3 bucket
Open the Amazon S3 console.
Choose Create bucket.
Enter a unique name for your bucket (for example, demo-customer-data-20250819).
In the Tags section, add the following tags:
Key: gdpr-scan, Value: true
Key: Business Function, Value: Sales – US
Key: Data Classification, Value: Confidential
Keep other settings as default and choose Create bucket.
Figure 6 S3 console showing new bucket creation with tags
Step 4: Upload sample data
In the S3 console, open your newly created bucket.
Choose Upload.
Create a new file named customer_orders.csv with the below content.
Upload this file to a folder named orders/ in your bucket.
Note: While we focus on S3 data sources in this walkthrough, the framework extends to other data stores, offering a unified approach for PII detection and compliance management, so organizations can automatically discover, catalog, and monitor sensitive data elements across your entire data ecosystem. For more information, see aws-samples/automated-datastore-discovery-with-aws-glue.
Best practices and operational excellence
As you implement this solution, consider these key practices for effective results:
Design your tagging strategy to capture essential business context about each data source. Implement automated tag enforcement through AWS Organizations for consistency across teams.
Monitor automated workflows regularly and configure retention policies for processed data to manage costs.
For enhanced security, configure VPC endpoints for services such as Amazon S3, DynamoDB, and other data sources. This keeps traffic within the AWS network, which is especially important when processing sensitive data. Verify that server-side encryption (SSE) is enabled on your data stores. This solution uses AWS Key Management Service (AWS KMS) keys for DynamoDB tables and SSE-S3 for S3 buckets by default, aligning with data-at-rest encryption best practices.
For teams with multiple AWS accounts, implement cross-account discovery and cataloging to maintain a comprehensive view of your data landscape.
Figure 15 Centralized Storage of Glue PII Detection Results in AWS Data Catalog
Clean up
To avoid ongoing charges and remove the resources created by this solution, follow these steps:
Empty and delete the S3 buckets created for sample data and AWS Glue assets.
Delete the AWS CloudFormation stacks in reverse order of creation:
Review your AWS account to ensure that all related resources have been removed.
Remember, deleting these resources will remove all data and configurations associated with this solution. Make sure that you have saved any important information before proceeding with the clean-up.
Conclusion
In this post, you learned how to build an automated data governance framework using AWS Glue Data Catalog. You set up detection, processing, and management layers that automatically discover, catalog, and classify your data sources.This approach improves how you manage sensitive data assets. Teams spend less time on manual discovery and categorization, freeing them to derive value from data. The system gives you current insights into your data landscape and automatically identifies sensitive data, creating a trusted source of truth that helps teams work efficiently while maintaining controls.You can extend this framework with custom sensitivity patterns for your industry. Its modular design supports continuous improvement and integrates with existing workflows. This turns data governance from a manual burden into an efficient process that scales with your organization.
There have been multiple notable supply chain attacks using the npm Registry since September: Shai-Hulud, Chalk/Debug, one abusing tea.xyz tokens, and recently axios. Thanks to community efforts involving the Amazon Inspector team, the Open Source Security Foundation, and others, the affected packages were quickly flagged, which reduced the impact of these incidents.
Supply chain attacks like Shai-Hulud exploit vulnerabilities on two fronts: compromised maintainer accounts that publish malicious packages, and consumer environments that download and execute those packages. The Shai-Hulud attack, shown in Figure 1, succeeded because maintainer credentials were compromised through phishing, enabling threat actors to publish malicious versions of popular packages. Incidents like these highlight the need for strong security practices within the software supply chain, and effective defense requires addressing both sides. Package maintainers need protections that prevent account compromise and limit sprawl when credentials are stolen. Package consumers need layered defenses that detect malicious packages, prevent their deployment, and limit damage when compromise occurs.
In this post, we explore best practices for package consumers. These practices are aligned with the AWS Well-Architected Framework – Security Pillar and you can use them to reduce exposure to similar threats and limit their impact if they occur.
Use temporary credentials and grant least privilege
When Shai-Hulud executed in developer environments and continuous integration and delivery (CI/CD) pipelines, it scanned for secrets such as npm tokens, GitHub tokens, and AWS Identity and Access Management (IAM) access keys. Long-term credentials exposed in this way enabled threat actors to propagate the malware further and access cloud resources. Recent incidents have shown organizations discovering multiple leaked IAM credential pairs, with concerns about additional exposed credentials and potential compromise of CI/CD pipelines.
Removing long-lived credentials from your developer environments and CI/CD pipelines reduces the scope of exposure in the event a system is compromised. For developers working locally, the new AWS CLI login command (aws login) simplifies the process of acquiring short-lived CLI credentials and removes the need to store long-lived credentials in configuration files. AWS IAM Identity Center also provides a straightforward way to acquire temporary credentials that expire automatically. For CI/CD pipelines, OpenID Connect (OIDC) federation with GitHub Actions, GitLab CI, or other platforms provide temporary credentials for each job without storing long-lived tokens. IAM can also federate AWS Identities to external services, allowing your AWS workloads to securely access external services without using long-term credentials. Temporary credentials expire automatically, limiting the window of exposure if a pipeline is compromised.
If you’re interacting with a third-party service that doesn’t support temporary credentials, consider storing the credentials to centralized storage using AWS Secrets Manager or AWS Systems Manager Parameter Store. Limit access to these secrets, require the use of temporary credentials, and apply automatic rotation and audit logging to reduce the risk of exposure of these credentials.
To reduce risk from credential exposure:
Use temporary credentials: Federate users from a central identity provider into AWS and use IAM roles for access. SEC02-BP02: Use temporary credentials.
Grant least privilege: Assign only the minimum permissions necessary and use temporary elevated permissions where higher privilege is occasionally required. SEC03-BP02: Grant least privilege access.
In the event of a security incident where credentials might be exposed, immediately rotate all long-term credentials to limit the scope of impact. Use Amazon GuardDuty and AWS CloudTrail to detect abnormal IAM activity and identify which credentials might have been compromised.
Implement defense in depth
Even with temporary credentials and least privilege, a single compromised account can enable threat actors to publish malicious packages or access sensitive resources. Defense in depth creates multiple layers of protection that work together to prevent sprawl after initial compromise. While adding approval workflows to every operation would dramatically decrease deployment speed, implementing them strategically for sensitive workloads provides balanced security.
The key principle is to ensure that if one credential or account is compromised, additional controls prevent that compromise from spreading across your organization. This includes multi-factor authentication (MFA) for access combined with different IAM roles for sensitive workloads. For single-developer open source projects, MFA becomes even more critical because there’s no separation of duties through multiple maintainers.
For package maintainers working in team environments, requiring multiple approvers to release packages to production creates separation of duties. However, developers can still trigger merge requests that initiate deployment pipelines, so multi-party approval should be implemented within the pipeline itself for sensitive deployments. This ensures that even if a developer’s credentials are compromised and they trigger a deployment, the pipeline requires additional approval before releasing to production.
For package consumers, multi-approval workflows in deployment pipelines help ensure that if a malicious package passes initial scanning, human review can catch suspicious changes before production deployment. Artifact signing provides a complementary cryptographic layer that works alongside these process controls.
The Shai-Hulud attack succeeded because compromised maintainer credentials allowed threat actors to publish malicious packages directly to the public npm registry. For package consumers, the defense is ensuring that packages pulled from public registries cannot reach production without verification. Artifact signing is one concrete implementation of this layered approach. By cryptographically binding a package or container image to the identity that produced it, signing creates a verification layer that is independent of the credential used to trigger the build—meaning a compromised developer credential alone isn’t sufficient to introduce an unverified artifact into your deployment pipeline.
Artifact signing as part of defense in depth
AWS Signer provides cryptographic signing for packages, creating an additional verification layer within your defense in depth strategy. The signing authorization model separates concerns: developer credentials shouldn’t have signing permissions. Only CI/CD pipeline roles should have signing permissions through the signer:StartSigningJob API. Signer uses FIPS 140-3 Level 3 validated hardware security modules (HSMs) to store signing keys, providing strong cryptographic protection.
The container image signing workflow, shown in Figure 2, demonstrates how signing integrates seamlessly into existing processes:
The benefits of Signer compared to building custom signing infrastructure include:
Fully managed: No need to build custom signing infrastructure or manage certificate lifecycle
Automated: Amazon ECR managed signing happens automatically on image push without manual steps
Centralized governance: Single signing profile can be used across multiple accounts and pipelines
Native integration: Built-in integration with Notation and Kyverno for signature verification in Amazon EKS
FIPS 140-3 Level 3 compliance: Meets stringent regulatory requirements for cryptographic operations
Audit logging for all signing operations enables detection of unusual patterns such as signing from new IP addresses, unusual times, or rapid succession of signing jobs. For every credential in your system, consider who can access what, how they prove their identity, and what second layer prevents sprawl if that credential is compromised. Artifact signing, combined with centralized storage and Software Bills of Materials (SBOMs), provides layered protection against tampering and malicious packages.
Centralize dependency management
By centralizing package and dependency management, you can validate and approve dependencies before they’re used in applications and quickly audit dependencies in the event of a supply chain security incident. Recent incidents have shown organizations discovering compromised npm packages in their internal artifact repositories, requiring rapid assessment of which applications might be affected.
On AWS, you can use AWS CodeArtifact to host and manage your organization’s software packages. You can use the package group configuration to define an approved list of upstream sources and block access to all others—a direct control against typosquatting attacks, where malicious packages are published under names that closely resemble legitimate ones. Rather than relying on developers to identify suspicious package names at install time, package group configuration enforces the boundary at the repository level. Centralization also helps you pin versions of dependencies to prevent automatic updates from pulling in malicious versions and quickly remove compromised dependencies across your software portfolio when an incident occurs.
For container images, Amazon ECR provides centralized image storage with AWS Key Management Service (AWS KMS) encryption and lifecycle policies. Combine Amazon ECR with Amazon Inspector scanning to continuously validate image integrity.
For npm packages specifically, provenance attestations provide a complementary control on the consumer side. Available since npm 9.5, npm provenance links a published package to the specific source repository and CI/CD workflow that produced it, using Sigstore as the underlying signing infrastructure. When a package is installed, the npm CLI can verify that the published artifact matches the attested build provenance—providing confidence that the package wasn’t tampered with between build and publication. For organizations consuming open source npm packages, checking for provenance attestations before adding a new dependency is a low-friction signal of supply chain integrity. Package maintainers publishing to npm can enable provenance by running npm publish with the –provenance flag from a supported CI/CD environment such as GitHub Actions.
Scan dependencies throughout the software development lifecycle
AWS provides services to help you scan dependencies continuously, from development through deployment:
In development: Kiro can perform software composition analysis during code reviews to identify vulnerable third-party code.
In code repositories and pipelines: Amazon Inspector scans first-party code, third-party dependencies, and Infrastructure as Code for vulnerabilities.
For container images: Amazon Inspector provides continuous vulnerability scanning of Amazon ECR images. Amazon Inspector can also be integrated directly into CI/CD pipelines to scan images before they are pushed to Amazon ECR or deployed, helping you block compromised dependencies earlier in the release cycle.
Traditional vulnerability scanners focus on known CVEs—publicly disclosed vulnerabilities with assigned identifiers. Supply chain attacks like Shai-Hulud involve malicious packages that function as zero-days: they’re intentionally crafted by threat actors and actively exploited before a CVE is assigned. Traditional vulnerability scanners that rely on CVE databases won’t detect these packages until they’ve been formally identified and catalogued, which can take days or weeks.
Detecting these requires behavioral analysis at scale and community collaboration, not just static signature matching. The operational scale of AWS—with threat intelligence from sources like MadPot and incident response data across millions of customers—enables detection of suspicious package behavior across multiple environments simultaneously. When a newly published package exhibits credential-harvesting behavior in multiple customer accounts within hours of publication, that cross-account signal enables rapid identification. These findings are contributed to community-maintained databases like the OpenSSF Malicious Packages Repository (github.com/ossf/malicious-packages), which assigns a formal identifier (MAL-ID) and shares it across the security community. For the tea.xyz token farming campaign, the average time from submission to formal identification was approximately 30 minutes. AWS services like Amazon Inspector participate in this community loop, contributing findings and ingesting newly assigned MAL-IDs to surface threats in your environment.
A related threat model worth understanding is the sleeper package: a package that appears benign at publication and activates malicious behavior only after a delay or trigger condition. Static analysis alone is insufficient to catch these packages because the malicious payload isn’t present or active at install time. Amazon Inspector behavioral analysis is specifically designed to detect this class of threat, complementing static vulnerability scanning.
Software Bills of Materials (SBOMs) in SPDX or CycloneDX format enable you to quickly assess exposure during incidents. When responding to supply chain incidents, use SBOMs to identify which applications contain compromised packages, prioritize remediation, and assess blast radius. In the Shai-Hulud incident, the compromised packages (MAL-2025-46974 and CVE-2025-59144) were identified early, providing actionable findings that customers could remediate quickly. Organizations that had scanning enabled but experienced alert fatigue may have missed critical alerts, highlighting the importance of proper alert routing and prioritization.
CloudTrail logging provides audit trails for credential access and API activity. When responding to supply chain incidents, review CloudTrail logs for specific events that indicate credential compromise or malicious activity: sts:AssumeRole calls from unexpected IP addresses or regions, secretsmanager:GetSecretValue or ssm:GetParameter calls from unfamiliar sources, ecr:PutImage from developer workstations bypassing CI/CD pipelines, lambda:UpdateFunctionCode outside normal deployment windows, iam:CreateAccessKey followed by immediate API activity, and codecommit:GitPush or codebuild:StartBuild from unusual IP addresses. When combined with Amazon EventBridge rules, you can trigger automated responses when Amazon Inspector detects malicious packages or when these unusual credential access patterns occur.
Organizations affected by recent supply chain attacks have used CloudTrail analysis to determine the scope of credential exposure and identify which resources might have been accessed by compromised credentials. This forensic capability is essential for understanding blast radius and ensuring complete remediation.
For additional guidance see the best practices in SEC04: Detection.
These components of a defense in depth strategy work together to prevent sprawl after initial compromise and help you to detect and respond to the event. Figure 4. shows how these fit together.
Recent incidents including Shai-Hulud, Chalk/Debug, and tea.xyz reflect ongoing efforts by threat actors to target the the package registries, CI/CD pipelines, and developer credentials for increased attack surface and propagation. A single compromised maintainer account or malicious package can propagate across thousands of consumer environments simultaneously. The controls described in this post are designed with that threat model in mind. Temporary credentials limit the value of stolen tokens, centralized dependency management and upstream blocking reduce the attack surface at the registry level, artifact signing ensures that even if a build pipeline is compromised, unsigned artifacts cannot reach production, and dependency scanning throughout your software lifecycle helps you identify compromised packages early, before they can impact you. Each layer narrows the window of opportunity for a threat actor.
Learn more
See the following blogs and workshops to dive deeper on this topic:
Organizations often struggle to enforce security and compliance requirements consistently across their cloud infrastructure. In one environment, a workload might be deployed in an AWS Region that was never approved for that class of data. In another, a security group might allow broader access than intended. Required tags might be missing. Encryption might be assumed but not configured. These gaps create risk, increase review effort, and make audits harder than they need to be.
Many organizations already have standards that describe what good infrastructure looks like. The more difficult problem is making sure those expectations are checked the same way across repositories, environments, and teams before infrastructure is deployed. Manual review helps, but it doesn’t scale when delivery moves faster and more teams provision infrastructure directly.
Policy as code helps address this problem. It turns control intent into preventive checks that run in delivery workflow.
A pattern-based policy model makes those checks more straightforward to review, maintain, and explain. Teams can organize policy checks around recurring control patterns such as required metadata, allowed configuration, exposure restriction, protection enforcement, and privilege constraint, as shown in Figure 1. This structure simplifies policy coverage across security, governance, risk, and compliance (GRC), and engineering teams.
This post shows you how to use Open Policy Agent (OPA) in continuous integration and continuous delivery (CI/CD) pipelines to validate Amazon Web Services (AWS) infrastructure changes before deployment. You will learn how to structure policy checks around recurring control patterns, fit those checks into a gated delivery workflow, and retain validation artifacts that support both release decisions and later audit review.
The Compliance Engineering and Automation team from AWS Security Assurance Services (AWS SAS) frequently helps customers implement policy as code as part of broader control design and compliance automation efforts. This post focuses on the pre-deployment layer. Runtime monitoring and post-deployment controls still matter, but they are outside the scope of this article.
Figure 1: Pattern-based policy as code in a gated delivery workflow
Organize policies around recurring patterns
Teams sometimes build rules one service at a time, which can make policy as code libraries difficult to review and extend as the library grows. Similar control requirements can be expressed differently across repositories, and teams lose a common way to discuss what the policies are enforcing.
A pattern-based approach organizes policies around recurring control intent rather than service-specific checks, as shown in Figure 2. This makes coverage more straightforward to review, explain, and evolve as infrastructure changes.
A practical set of patterns includes:
Required metadata – for tags and other fields used for ownership, support, cost allocation, and automation.
Allowed configuration – for approved Regions, accepted deployment boundaries, and other approved settings.
Exposure restriction – for configurations that make infrastructure more reachable than intended, such as public ingress or internet-facing resources in the wrong environment.
Protection enforcement – for baseline safeguards such as encryption, logging, or deletion protection.
Figure 2: Recurring control patterns used to organize policy as code checks
Where OPA fits in a layered governance model
This post focuses on the preventive layer. You still need runtime controls, drift monitoring, remediation workflows, and compliance reporting. On AWS, AWS Organizations, AWS Control Tower, AWS Config, and AWS Security Hub remain important after resources exist.
OPA fits earlier in the process and validates that infrastructure changes align with expectations. OPA evaluates structured input (HashiCorp Terraform plan JSON) against policy logic. It doesn’t replace AWS governance services that provide organizational guardrails, continuous monitoring, and resource level enforcement after resources exist.
As shown in Figure 3:
OPA – Checks proposed changes before deployment
AWS Organizations and Control Tower – Establish organizational guardrails
AWS Config and Security Hub – Provide visibility and monitoring after resources exist
Service-level protections – Enforce settings at the resource boundary
How to implement policy validation in your CI/CD pipeline
Use the following steps to integrate OPA policy evaluation into your delivery workflow:
Submit a change through a pull request or merge request.
Run early validation checks such as formatting, syntax validation, and dependency checks.
Generate a Terraform plan and convert it to JSON format.
Evaluate the plan (JSON format) against the shared OPA policy library.
Publish the validation report as an artifact.
Run additional automated quality checks as needed.
Use the validation artifact during approval decisions for higher-risk environments.
Deploy approved changes.
Continue post-deployment monitoring through AWS-native governance services.
Quality gates provide automated pass or fail results based on defined criteria. Approval gates control whether a change moves into a protected environment. This separation matters—manual approval isn’t the first place where anyone notices missing tags, a disallowed AWS Region, or public ingress. Automated checks identify those issues earlier. OPA belongs in the automated gate layer. Its output also feeds the approval process.
Structure your policy library by control domain and intent
A pattern-based library structure, as shown in the following sample, keeps the policy model closer to how teams talk about controls.
A compliance engineer might describe a requirement as mandatory metadata. A cloud engineer might describe the same requirement as a tagging standard. The pattern structure helps both teams talk about the same thing.
Example 1: Enforce secure transport for Amazon S3
This example demonstrates the protection enforcement pattern for Amazon Simple Storage Service (Amazon S3). The goal is to verify that S3 bucket access is protected in transit by requiring a bucket policy that denies requests when aws:SecureTransport is set to false.
The policy checks two things: whether an S3 bucket policy includes a deny statement that blocks non-encrypted requests, and whether an S3 bucket has any corresponding bucket policy at all. The rule evaluates both create and update actions in the Terraform plan JSON.
This example uses an explicit deny rather than an allow statement for secure transport. An explicit deny overrides allow statements that might exist elsewhere in the policy set, making it the stronger enforcement pattern.
package compliance.amazon_s3.ssl

import future.keywords.in
import future.keywords.contains
import future.keywords.if

# Deny: S3 bucket policy missing SecureTransport deny statement
deny contains msg if {
    resource := input.resource_changes[_]
    resource.type == "aws_s3_bucket_policy"
    is_create_or_update(resource.change.actions)

    policy_value := resource.change.after.policy
    policy := json.unmarshal(policy_value)

    not has_secure_transport_deny(policy)

    msg := sprintf(
        "[S3-OPA-1] Resource '%s' does not enforce SSL/TLS. Bucket policy must include a Deny statement with Condition Bool aws:SecureTransport set to \"false\".",
        [resource.address]
    )
}

# Deny: S3 bucket created without any corresponding bucket policy
deny contains msg if {
    resource := input.resource_changes[_]
    resource.type == "aws_s3_bucket"
    is_create_or_update(resource.change.actions)

    bucket_name := resource.change.after.bucket
    not has_bucket_policy(bucket_name)

    msg := sprintf(
        "[S3-OPA-1] Resource '%s' (bucket '%s') has no bucket policy. A bucket policy with a Deny statement for aws:SecureTransport \"false\" is required.",
        [resource.address, bucket_name]
    )
}

is_create_or_update(actions) if { actions[_] == "create" }
is_create_or_update(actions) if { actions[_] == "update" }

has_bucket_policy(bucket_name) if {
    bp := input.resource_changes[_]
    bp.type == "aws_s3_bucket_policy"
    is_create_or_update(bp.change.actions)
    bp.change.after.bucket == bucket_name
}

has_secure_transport_deny(policy) if {
    stmt := policy.Statement[_]
    stmt.Effect == "Deny"
    stmt.Condition.Bool["aws:SecureTransport"] == "false"
    stmt.Principal == "*"
    action := stmt.Action
    action == "s3:*"
}
When you adapt this example, decide whether you want to require one exact policy shape or support several equivalent forms of enforcement. A strict rule is more straightforward to reason about, but it might create false positives if teams already use alternate policy structures that achieve the same outcome.
Example 2: Restrict public ingress on sensitive ports
This example implements the exposure restriction pattern. The goal is to identify Amazon Virtual Private Cloud (Amazon VPC) security group configurations that allow public ingress on sensitive ports before those rules are deployed.
The policy evaluates both inline aws_security_group ingress rules and standalone aws_security_group_rule resources, because customer repositories often use both modeling styles.
This example checks directly for public ingress on sensitive ports rather than trying to infer whether later controls might reduce actual exposure. Security group rules are a direct expression of intended network reachability, making them the right place to enforce this pattern early.
package compliance.amazon_vpc.ingress

import future.keywords.in
import future.keywords.contains
import future.keywords.if

# Sensitive ports that must not be open to the internet
sensitive_ports := {22, 3389, 5432}

# Deny: aws_security_group with inline ingress open to 0.0.0.0/0 on sensitive ports
deny contains msg if {
    resource := input.resource_changes[_]
    resource.type == "aws_security_group"
    is_create_or_update(resource.change.actions)

    ingress := resource.change.after.ingress[_]
    ingress.cidr_blocks[_] == "0.0.0.0/0"

    port := sensitive_ports[_]
    ingress.from_port <= port
    ingress.to_port >= port

    msg := sprintf(
        "[VPC-OPA-1] Resource '%s' allows ingress from 0.0.0.0/0 on port %d. Restrict access to specific CIDR ranges.",
        [resource.address, port]
    )
}

# Deny: aws_security_group_rule with type "ingress" open to 0.0.0.0/0 on sensitive ports
deny contains msg if {
    resource := input.resource_changes[_]
    resource.type == "aws_security_group_rule"
    is_create_or_update(resource.change.actions)

    resource.change.after.type == "ingress"
    resource.change.after.cidr_blocks[_] == "0.0.0.0/0"

    port := sensitive_ports[_]
    resource.change.after.from_port <= port
    resource.change.after.to_port >= port

    msg := sprintf(
        "[VPC-OPA-1] Resource '%s' allows ingress from 0.0.0.0/0 on port %d. Restrict access to specific CIDR ranges.",
        [resource.address, port]
    )
}

is_create_or_update(actions) if { actions[_] == "create" }
is_create_or_update(actions) if { actions[_] == "update" }
When you adapt this example, review which ports to treat as sensitive, whether both IPv4 and IPv6 exposure need checking, and how to handle approved exceptions.
Example 3: Enforce least privilege trust policy for IAM roles
This example implements the privilege constraint pattern for IAM role trust policies. The goal is to identify trust relationships that allow overly broad principals to assume a role. The policy inspects the assume_role_policy document for aws_iam_role resources and looks for wildcard principals in three valid representations: Principal is "*", Principal.AWS is "*", and Principal.AWS is an array containing "*". A wildcard principal allows a broader set of callers than most environments intend to permit. By treating wildcard principals as the prohibited pattern, the rule enforces a safer default and returns a clear result that reviewers can understand quickly.
package compliance.amazon_iam.trust

import future.keywords.in
import future.keywords.contains
import future.keywords.if

# Deny: IAM role with wildcard principal in trust policy
deny contains msg if {
    resource := input.resource_changes[_]
    resource.type == "aws_iam_role"
    is_create_or_update(resource.change.actions)

    policy_value := resource.change.after.assume_role_policy
    policy := json.unmarshal(policy_value)

    stmt := policy.Statement[_]
    stmt.Effect == "Allow"
    has_wildcard_principal(stmt)

    msg := sprintf(
        "[IAM-OPA-2] Resource '%s' has a wildcard principal in its trust policy. Specify explicit account ARNs, service principals, or federated providers instead of \"*\".",
        [resource.address]
    )
}

# Principal is directly "*"
has_wildcard_principal(stmt) if {
    stmt.Principal == "*"
}

# Principal.AWS is "*"
has_wildcard_principal(stmt) if {
    stmt.Principal.AWS == "*"
}

# Principal.AWS is an array containing "*"
has_wildcard_principal(stmt) if {
    stmt.Principal.AWS[_] == "*"
}

is_create_or_update(actions) if { actions[_] == "create" }
is_create_or_update(actions) if { actions[_] == "update" }
When you adapt this example, decide what least privilege means for your IAM trust model. The key design choice is whether your policy checks for a single prohibited pattern or validates trust relationships against an approved set of trusted principals and conditions.
AWS Labs provides IAM Policy Autopilot, an open-source Model Context Protocol (MCP) server and command-line tool that helps generate baseline identity-based IAM policies from application code. That is adjacent to the pattern shown here —IAM Policy Autopilot helps with policy generation, while this example focuses on validating whether IAM role trust policies are scoped appropriately in infrastructure changes.
CI/CD implementation examples
The following examples show the same operating model in two common CI/CD systems. The syntax changes, but the sequence stays the same: validate, plan, evaluate policy, retain the artifact, and use the result during promotion and approval. These examples assume OPA is installed in your CI/CD environment, the opa-policies directory contains your policy library, and Terraform is configured with appropriate credentials.
Retain validation artifacts for review and audit support
In mature delivery workflows, policy results don’t disappear into pipeline logs but are retained as validation artifacts. Those artifacts help reviewers decide whether a change is ready for approval, supports exception handling by showing which controls failed and why, and can stay with the change record for later audit discussions. At a minimum, the artifact identifies the change or pipeline run, the evaluated scope, the policy package or version, the checks that ran, and the pass or fail results.
Test the policy model like software
The first few rules are usually straightforward.The real work starts when the library grows and multiple teams depend on it. Testing includes:
Positive and negative test cases – Each policy has cases that show valid input and cases that show expected failures.
Regression coverage – Shared helpers need regression coverage.
Realistic fixtures – Terraform plan fixtures look like real changes rather than tiny made-up samples.
Impact analysis – When a rule changes, teams can tell quickly what else might be affected.
If developers stop trusting the results, they stop treating policy as a useful mechanism.
A phased approach to rolling out policy checks
You don’t need broad coverage on day one. A phased rollout works better than an all at once enforcement approach.
Phase 1: Assess and pilot
Start in advisory mode so teams can see results without being blocked.
Identify two or three high-confidence patterns such as required metadata, approved Regions, or public exposure restrictions.
Run OPA against existing pipelines and review the output for accuracy.
Phase 2: Begin enforcement
Enforce the small set of high-confidence patterns after the output is stable and the failures are useful.
Integrate validation artifacts into your approval workflow.
Establish ownership and exception handling processes for shared packages.
Phase 3: Operationalize and expand
Formalize versioning for shared policy packages.
Expand pattern coverage based on team feedback and organizational priorities.
Policy as code helps narrow the distance between what an organization says it expects and what its delivery system checks. By implementing these OPA patterns in your CI/CD pipelines, you can build a preventive layer that evaluates infrastructure changes before deployment. With a pattern-based library, validation artifacts, and clear ownership, policy as code becomes a repeatable way to help translate control intent into day-to-day delivery, while AWS governance services continue to provide visibility and monitoring after resources exist.
To learn more about policy as code and AWS governance capabilities, see:
Selecting the right SQL processing solution for large-scale data analytics is a critical decision for organizations. As data volumes grow exponentially, the technology landscape has evolved to offer diverse options for processing and analyzing this information efficiently. This post presents a systematic framework for evaluating and benchmarking SQL processing engines on AWS, using Apache JMeter to conduct practical performance testing at scale.
The AWS analytics ecosystem
AWS offers a rich portfolio of SQL processing solutions to meet various analytical needs:
Serverless query services – Amazon Athena is a serverless, interactive query service that uses standard SQL to analyze data in Amazon Simple Storage Service (Amazon S3), offering automatic scaling, parallel query execution, and pay-per-query pricing with no infrastructure management required
Data warehouse solutions – Amazon Redshift offers scalable, high-performance cloud data warehousing with serverless options, zero-ETL integrations, AI-powered query assistance, and seamless machine learning (ML) integration for modern analytics at scale
Managed open source engines – Amazon EMR supports Apache Spark SQL, Apache Trino (formerly PrestoSQL), and other distributed query frameworks
Self-managed options – You can deploy open source engines like Apache Spark, Apache Flink, and Trino on Amazon Elastic Kubernetes Service (Amazon EKS) for greater control
Partner solutions – You can access specialized big data analytics tools through AWS Marketplace
These options are further enhanced by modern open table formats such as Apache Iceberg, Delta Lake, and Apache Hudi, which bring crucial enterprise features like ACID (Atomicity, Consistency, Isolation, and Durability) transactions, schema evolution, and time travel capabilities to data lakes. These SQL processing solutions operate under the AWS Shared Responsibility Model. AWS manages the security of the underlying infrastructure and services, and customers are responsible for secure configuration, access management, and data protection within their testing environments. This division of responsibility remains important when evaluating and benchmarking different SQL engines. Proper security configuration and implementation by customers is essential for maintaining a secure analytics environment.
Evaluation challenges in SQL engine selection
The rich ecosystem of SQL processing options creates significant evaluation challenges. Each SQL engine employs unique architectural approaches and optimization strategies, making direct comparisons complex. Organizations embarking on this evaluation journey face several interconnected obstacles:
Creating environments that accurately reflect production scenarios
Developing test datasets that mirror real-world data characteristics and volumes
Replicating real-world query patterns and concurrency levels
Maintaining uniform testing conditions across different engine architectures
Controlling infrastructure expenses throughout the evaluation process
Performance considerations at petabyte scale
When evaluating solutions for petabyte-scale deployments, the complexity intensifies considerably. Several critical factors come into play:
Resource management – Distributed SQL engines require precise balancing of CPU, memory, and storage resources. Suboptimal resource allocation can lead to query failures and performance degradation, particularly as data volumes grow.
Data distribution patterns – How data is distributed across partitions or nodes significantly impacts query performance. Data skew can create processing bottlenecks, with some nodes handling disproportionate workloads while others remain underutilized.
Concurrency handling – High-concurrency environments demand sophisticated workload scheduling and resource isolation mechanisms. The ability to maintain consistent performance under varying concurrent loads becomes a critical differentiator between solutions.
Mean, median, and percentile response times (particularly p90 and p95)
Query throughput under varying concurrency levels
Scalability characteristics across diverse workload types
Resource utilization efficiency during peak loads
Limitations of traditional benchmarks
Although industry-standard benchmarks like TPC-DS and TPC-H provide valuable insights, our experience with multiple customer engagements has shown that tailored, workload-specific testing often reveals performance characteristics not captured by these standardized tests. This is especially true for complex, multi-tenant environments with diverse query patterns. Organizations that complement standard benchmarks with workload-specific testing typically experience shorter proof-of-concept cycles, optimized evaluation costs, and more efficient testing operations. This comprehensive approach helps reduce uncertainty in the final solution selection process.
Prerequisites
Before you dive into the evaluation process, make sure you have the following prerequisites:
An AWS account with appropriate permissions to create and manage Amazon Elastic Compute Cloud (Amazon EC2) instances and access the SQL engines you plan to benchmark.
Basic familiarity with AWS services, particularly Amazon EC2 and the SQL engines you intend to evaluate (such as Athena, Amazon Redshift, or Amazon EMR).
Experience with SQL and data analytics concepts.
Access to the SQL engines you choose to benchmark. This post assumes you’ve already set up the engines you want to test. For setup instructions, refer to the AWS documentation for each service.
A dataset suitable for your benchmarking needs. Dataset creation and loading are not covered in this post. Build petabyte-scale synthetic test data with Amazon EMR on EC2 provides prescriptive guidance to generate test datasets at scale. Make sure your test datasets are stored in S3 buckets with encryption enabled (using SSE-KMS or SSE-S3) and that all service connections use TLS for data in transit.
Benefits of Apache JMeter
As organizations scale their analytics workloads to petabyte levels, there is a growing need for a robust, structured approach to SQL query performance testing. Although many organizations develop custom testing frameworks or use various benchmarking tools, these approaches often lack standardization and can be difficult to replicate across different SQL engines. The complexity of modern data architectures, combined with the variety of available SQL processing solutions, demands a systematic evaluation methodology. Apache JMeter emerges as a powerful solution to address this challenge. Though traditionally known for web application testing, JMeter’s extensible architecture and robust feature set make it particularly well-suited for SQL performance testing at scale.JMeter offers several advantages for evaluating SQL engines:
Support for multiple protocols and connections
Ability to simulate complex concurrent workloads
Built-in performance metrics and reporting
Extensible architecture for custom testing scenarios
Integration capabilities with continuous integration and continuous delivery (CI/CD) pipelines
Through this proposed framework, which has been validated across multiple customer engagements at petabyte scale, we aim to help organizations make more informed decisions when selecting a SQL processing solution. Our experience working with customers to assess various AWS Analytics services and open source solutions has demonstrated that a systematic evaluation approach significantly reduces proof-of-concept cycles and optimizes resource investments. This framework has helped organizations effectively evaluate services like Athena, Amazon Redshift, and Amazon EMR, alongside open source solutions such as Trino on Amazon EKS, based on their specific workload profiles and performance requirements.With this methodology, organizations can accomplish the following:
Navigate the complex landscape of large-scale data processing technologies
Reduce proof-of-concept cycles from months to weeks
Minimize infrastructure costs during evaluation phases
Make data-driven decisions about technology selection
Better align technology choices with business requirements
Establish repeatable testing patterns for future evaluations
Testing methodology in practice
A successful SQL engine evaluation requires understanding and replicating real-world workload patterns. Our methodology, refined through numerous customer engagements, focuses on comprehensive testing across multiple dimensions while remaining adaptable to specific organizational needs.
Query pattern selection
We begin by selecting representative query patterns that mirror production workloads:
Aggregation queries that summarize large datasets using operations like SUM, AVG, and COUNT
Complex join operations that test the engine’s ability to combine data efficiently across multiple tables
String operations that evaluate text processing capabilities
Nested queries that assess the engine’s optimization capabilities for complex query structures
A carefully selected set of 8–10 queries typically provides sufficient coverage while keeping the evaluation manageable. These should reflect your actual workload characteristics and business requirements.
Data volume variations
Testing across different data volumes is important for understanding scalability characteristics. We structure our tests around varying data scan ranges:
Small-scale scans – Queries accessing 1–7 days of data (megabytes to gigabytes)
Large-scale scans – Queries spanning 14–30 days (terabytes to petabytes)
This approach evaluates both I/O efficiency with large datasets and metadata handling with smaller, frequent queries, helping understand how services like Amazon EMR, Amazon Redshift, or Athena optimize query execution across different access patterns.
Concurrency testing
Real-world analytics environments rarely process single queries in isolation. Our methodology incorporates the following features:
Progressive concurrency testing starting at lower levels (typically 16, 32, 64, and 128 parallel queries), though these numbers can be adjusted based on your test infrastructure capacity and specific requirements. We recommend starting with smaller concurrency levels and gradually scaling up to understand performance characteristics
Varied query complexity and frequency (referred to as query weights) to simulate realistic workload distributions. This means some queries are run more often or are more resource-intensive than others, mimicking real-world usage patterns.
Mixed query patterns running simultaneously to test resource management.
Consistent execution across different date ranges to evaluate scaling behavior.
This approach is particularly important when evaluating managed services like the workload management capabilities of Amazon Redshift or the resource allocation strategies of Amazon EMR.
Query weight distribution
Production environments typically see varying frequencies of different query types. Our framework incorporates weighted query distribution to simulate real-world scenarios more accurately. In a typical distribution, frequent lightweight queries might represent 60% of the workload, complex analytical queries might comprise 30%, and resource-intensive data processing operations might make up the remaining 10%.This weighted approach makes sure performance testing reflects actual usage patterns rather than artificial benchmarking scenarios. The exact distribution should mirror your organization’s specific workload patterns.
Sequential vs. concurrent testing
Our methodology implements two distinct testing phases:
Tests different concurrency levels to identify scaling limitations
Evaluates resource management capabilities of different engines
JMeter efficiently implements both testing phases while maintaining consistent test conditions across SQL engines. Its ability to handle various JDBC connections makes it particularly suitable for testing AWS analytics services.Through this structured approach, organizations can gather comprehensive performance data reflecting their specific use cases, enabling informed SQL engine selection decisions while maintaining core principles of systematic evaluation and realistic workload simulation.
Test plans
To evaluate SQL engines’ performance under varying workloads, we designed two test scenarios: sequential and concurrent execution plans. Each scenario was executed across different data volumes by adjusting the query date range filters to cover 1, 7, 14, and 30 days. These variations simulate typical analytical workloads with progressively increasing data sizes.For sequential runs, each test was treated as a distinct batch, grouping all queries (Query 1 to Query 9) under the same date range—each query will scan data for 1, 7, 14, and 30 days with appropriate date filtering in the query’s where predicate. We used JMeter to capture average query response times for each batch. This configuration was run three times, and the final metrics reflect the average response time across these iterations to ensure reliability and account for environmental variance.Although three iterations provide initial insights, if you observe significant variations in results (typically more than 10% deviation between runs), consider expanding to 10 or more iterations. This additional sampling helps establish statistical significance, identify true performance patterns, and distinguish outliers (beyond three standard deviations) from normal variations. Document any consistent anomalies, because they may indicate important performance or security considerations for your specific environment.The following table shows the sample test plans template for the sequential test plan run.
Dataset Time Range
Run
Query Weights
Query 1
Query 2
Query 3
Query 4
Query 5
Query 6
Query 7
Query 8
Query 9
1 day
Run 1
Run 2
Run 3
Avg
7 days
Run 1
Run 2
Run 3
Avg
14 days
Run 1
Run 2
Run 3
Avg
30 days
Run 1
Run 2
Run 3
Avg
For the concurrent test plan, we introduced a probabilistic weighted distribution to the queries (Query 1 to Query 9), simulating a more realistic production-like environment where query frequency varies based on business relevance and usage patterns. This added a layer of complexity to better reflect how the SQL engine would perform under real-world concurrent access patterns.The following table shows the sample test plans template for the concurrent test plan run.
Dataset Time Range
Concurrent Runs
Query Weights
Query 1
Query 2
Query 3
Query 4
Query 5
Query 6
Query 7
Query 8
Query 9
1 days
8
11%
11%
11%
11%
11%
11%
11%
11%
11%
16
10%
5%
24%
5%
5%
5%
24%
14%
10%
32
8%
3%
24%
5%
5%
5%
24%
16%
8%
64
7%
3%
24%
6%
4%
6%
26%
16%
9%
128
1%
4%
19%
8%
5%
7%
14%
20%
22%
*7 days
8
11%
11%
11%
11%
11%
11%
11%
11%
11%
16
10%
5%
24%
5%
5%
5%
24%
14%
10%
32
8%
3%
24%
5%
5%
5%
24%
16%
8%
64
7%
3%
24%
6%
4%
6%
26%
16%
9%
**128
1%
4%
19%
8%
5%
7%
14%
20%
22%
14 days
8
11%
11%
11%
11%
11%
11%
11%
11%
11%
16
10%
5%
24%
5%
5%
5%
24%
14%
10%
32
8%
3%
24%
5%
5%
5%
24%
16%
8%
64
7%
3%
24%
6%
4%
6%
26%
16%
9%
128
1%
4%
19%
8%
5%
7%
14%
20%
22%
30 days
8
11%
11%
11%
11%
11%
11%
11%
11%
11%
16
10%
5%
24%
5%
5%
5%
24%
14%
10%
32
8%
3%
24%
5%
5%
5%
24%
16%
8%
64
7%
3%
24%
6%
4%
6%
26%
16%
9%
128
1%
4%
19%
8%
5%
7%
14%
20%
22%
For example, for configuration of *7 days concurrent run with **128 concurrency, the proposed configuration distributes Query 1 to Query 9 with appropriate weighted submissions such that Query 9 is executed the greatest number of times in the overall 128 executions submitted across all 9 queries for this run.
JMeter setup
To begin, you must set up JMeter on a machine that can handle the desired test load. An EC2 instance is a flexible and cost-effective option. Choose an instance type with sufficient vCPUs to support your maximum planned concurrency. For example, a c6i.4xlarge or higher is typically suitable for moderate to high throughput testing scenarios. For the operating system, you might choose Amazon Linux, which is optimized for AWS. For production-grade testing environments, deploy the JMeter EC2 instance in a private subnet of a virtual private cloud (VPC) with appropriate security groups that allow only required connections. This network isolation helps maintain security while executing performance tests. Consider using Amazon Virtual Private Cloud (Amazon VPC) endpoints for secure access to AWS services.
After the instance is provisioned, install Java (Java 17 LTS or Java 21 LTS) and download the latest version of JMeter. Be sure to configure the system with appropriate JVM options to allocate sufficient heap memory for large-scale test executions. Refer to Getting Started to learn more.
# Install Java
sudo yum update -y # For Amazon Linux
sudo yum install java-17-amazon-corretto -y

# Download JMeter and place the appropriate jdbc driver for the engine of your selection under lib folder
wget https://downloads.apache.org//jmeter/binaries/apache-jmeter-5.6.3.tgz
tar -xvzf apache-jmeter-5.6.3.tgz
cd apache-jmeter-5.6.3/lib

# Launch JMeter in GUI mode (if using a GUI-capable setup) or use CLI for remote testing
./bin/jmeter
JMeter concepts
Before you create test plans in JMeter, it’s important to understand a few foundational concepts that influence how your test plan behaves—such as thread groups, user-defined variables, and JDBC connection. These components enable the simulation of real-world query loads, including concurrency and pacing.
Test plans
The test plan is the top-level container for a JMeter test. It defines the overall testing strategy, including the queries to execute, their parameters, and the concurrent user behavior. These plans are represented as jmx files that can then be used for CLI-based execution. JMeter supports both GUI and CLI modes. It is highly recommended that you use the JMeter GUI primarily for creating test plans as jmx, and use the CLI for large load tests. You can also run thread groups consecutively for sequential execution. The default behavior is to run all thread groups in parallel suited for concurrent execution. Refer to Building a Test Plan to learn more about options available with test plans.
User-defined variables
User-defined variables are global parameters that you can reuse throughout the test plan. They are helpful for defining database credentials, server URLs, or query parameters. For example:DB_URL=jdbc:trino://trino-cluster.example.com:8889?SSL=true #Enable SSL/TLS
A thread group represents a group of virtual users (threads) executing test actions. Each thread simulates a single user sending requests to the SQL engine. This can be used to simulate concurrent runs. For example, in the preceding template, Query 3 has 19% weightage across 128 runs. This means .19*128=25 total runs, so we set the thread group to 25.
JDBC connection configuration
JDBC connection configuration sets up the database connection for the test. It specifies the database URL, driver, and credentials required for executing SQL queries. Key fields to configure are database URL and JDBC driver class. The following table summarizes the different configuration settings.
The JDBC request executes SQL queries against the database using the configuration defined in the JDBC connection configuration.
For example, following command runs the JMeter in CLI mode:
# Run benchmarks in CLI mode
./jmeter -n -t <path_to>.jmx -l <local path for log>.log -e -o <local path for>/output/
The output folder will contain an HTML report with different statistics. The following screenshot illustrates 128 concurrent runs.
Monitoring and logging
For comprehensive visibility and audit requirements, enable AWS CloudTrail logging, VPC Flow Logs, and service-specific logs (like Amazon S3 access logs). These logs can be centralized in Amazon CloudWatch Logs for monitoring and analysis. This provides proper audit trails while evaluating different SQL engines and helps track access patterns and potential security events.
Post-test steps
After running your JMeter tests, proceed with the following steps:
Review the HTML report’s key metrics, including response times, throughput, and error rates across different query types and concurrency levels.
Run identical test plans across your candidate SQL engines for direct performance comparison.
Refine your test plans based on initial findings, focusing on areas where performance differences are significant.
Factor in the cost implications alongside performance metrics to make a balanced decision.
These steps can help you systematically evaluate and select the most suitable SQL engine for your analytics workloads.
Resources
In the preceding steps, we walked through a UI-based setup for JMeter along with test plans. We have created a few sample JMeter test plans for both sequential and concurrent runs along with sample test reports. You can modify the plans to fit your needs.
After you complete your benchmarking process, clean up the resources to avoid unnecessary costs:
Stop or delete the EC2 instances used for running JMeter.
Depending on which SQL engines you used for testing, clean up active resources.
Review your AWS Management Console to confirm no active resources remain.
If you created test datasets in Amazon S3 or other storage services specifically for this benchmarking, consider deleting them if they’re no longer needed.
Although JMeter test plans and results don’t incur AWS costs, organize or delete local files as needed for your record-keeping.
Summary
Selecting the right SQL processing solution for large-scale analytics demands a systematic, data-driven approach. Our JMeter framework can help organizations effectively evaluate different SQL engines by simulating real-world workload patterns across various query types, data volumes, and concurrency levels. This methodology reduces proof-of-concept cycles and provides insights beyond traditional benchmarks, helping you assess managed AWS services like Athena and Amazon Redshift and open source solutions on Amazon EKS.
About the authors
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.