Tag Archives: Advanced (300)

Build petabyte-scale synthetic test data with Amazon EMR on EC2

Post Syndicated from Anubhav Awasthi original https://aws.amazon.com/blogs/big-data/build-petabyte-scale-synthetic-test-data-with-amazon-emr-on-ec2/

As you scale your data systems, you face a challenge: how to test thoroughly without putting customer data at risk. Using production data for testing can expose sensitive customer information to unauthorized access or breaches. For customers in regulated industries like finance and healthcare, this risk isn’t only a concern. It’s unacceptable. A data breach during testing could compromise their privacy, damage their trust, and expose organizations to significant compliance penalties. Synthetic test data solves this problem by generating artificial datasets that replicate the structure and patterns of real data without containing any actual customer information. This approach means you can test performance, validate data pipelines, and develop new features while ensuring that customer data remains protected and compliance requirements are met.

As data volumes grow from terabytes to petabytes, the architecture for generating synthetic data must evolve to meet increasing demands for scale, performance, and data quality. In this post, we show how you can build a scalable synthetic data generation solution using Amazon EMR, Apache Spark, and the Faker library.

The challenge of synthetic data generation

Traditional benchmark datasets like TPC-DS provide standardized schemas and predetermined data volumes for consistent testing environments across different systems. However, they fall short in meeting real-world testing requirements. These benchmarks don’t capture industry-specific patterns or the complex relationships found in actual production data. Their rigid schemas and simplified distributions fail to reflect business requirements, and scaling them while maintaining data consistency proves difficult. Perhaps most critically, generating massive datasets with traditional approaches requires specialized architectures to avoid proportional increases in compute costs and time.

Requirements for production-grade synthetic data

Effective workload validation demands synthetic data that mirrors production distributions while maintaining referential integrity across related tables and entities. The generation process must scale horizontally to accommodate growing data volumes while delivering deterministic results. Given identical input parameters, the system should produce the same dataset across multiple runs, supporting consistent testing cycles and comparative analysis.

Beyond technical requirements, synthetic data addresses compliance needs by minimizing exposure of personally identifiable information (PII) and protected health information (PHI) in non-production environments. This approach satisfies GDPR, HIPAA, and CCPA requirements while supporting secure cross-border data transfer, regular stress testing without compromising sensitive information, and providing an audit-friendly alternative to data masking that preserves analytical properties.

Solution overview

Architecting a synthetic data generation system that scales from terabytes to petabytes requires balancing several competing demands: the system must scale horizontally while maintaining data quality, generate large volumes efficiently, manage compute and storage resources cost-effectively, and support various schemas and output formats.

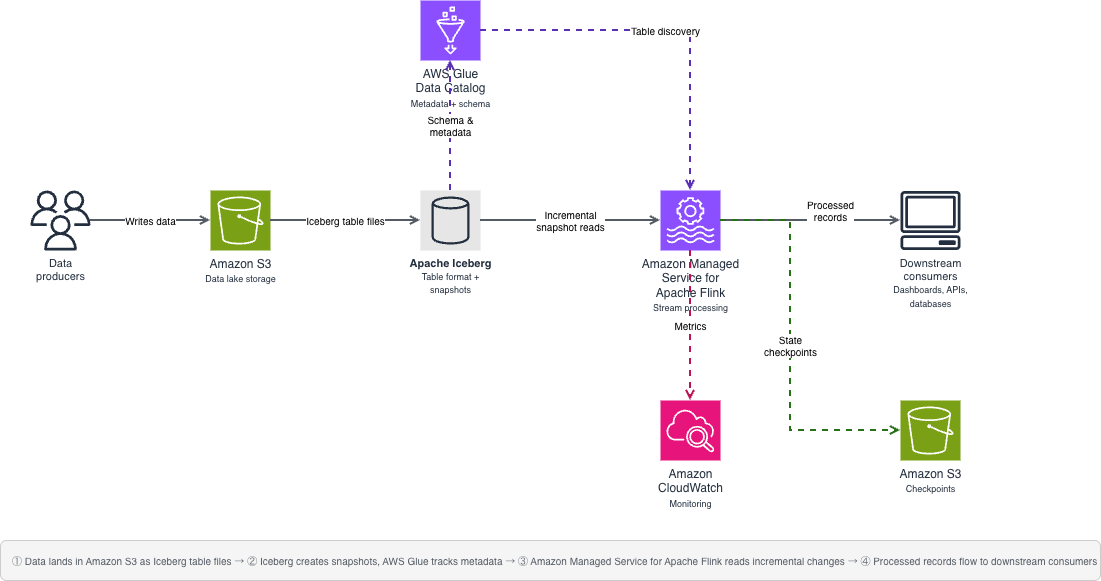
Our architecture addresses these challenges through four core components. Apache Spark on Amazon EMR provides the distributed computing framework necessary for large-scale generation. The Faker library offers synthetic data generation functions that integrate with Spark. Amazon Simple Storage Service (Amazon S3) with Apache Iceberg serves as the storage layer. We chose Iceberg for its schema and partition evolution capabilities without data rewrites, atomic transactions for consistency, precise time travel features for reproducible testing, and optimized performance at extreme scale. Amazon EMR handles dynamic resource allocation and cluster management.

The following diagram illustrates the solution architecture.
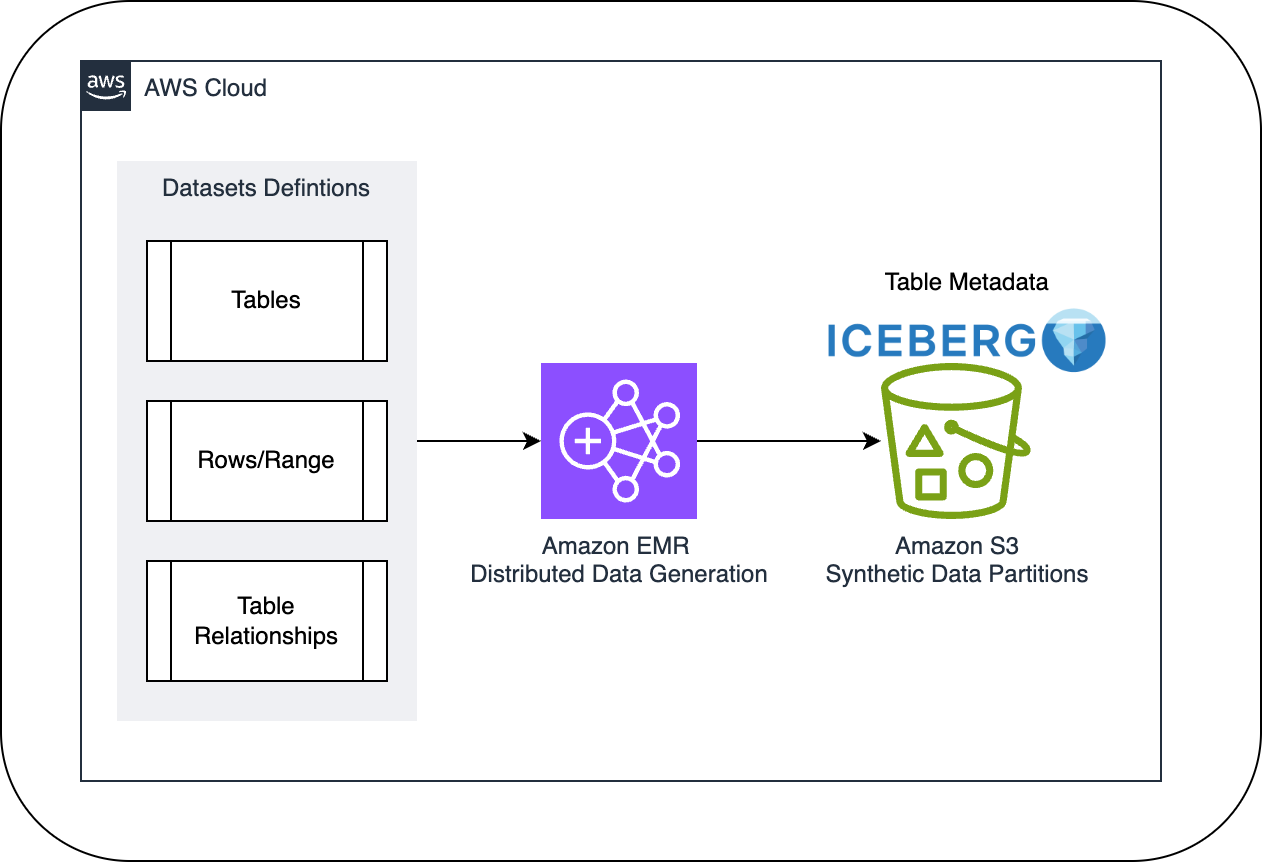
Solution architecture showing Amazon EMR generating synthetic data with Apache Spark and Faker, storing results in Amazon S3 with Apache Iceberg

Synthetic data generation at scale with Amazon EMR

Amazon EMR emerges as a particularly powerful solution for this use case, offering several advantages that directly address our requirements. It facilitates scaling of compute resources through instance fleets and Spot Instances, which can reduce costs by up to 90% compared to On-Demand pricing. The service provides built-in performance optimization for Spark applications with real-time monitoring through Amazon CloudWatch integration.

The managed infrastructure reduces operational overhead by handling the underlying Spark ecosystem and cluster lifecycle, while still providing control over scaling policies, instance types, and configurations. Integration with Amazon S3, AWS Glue, and Amazon Athena facilitates end-to-end data generation and testing workflows. Support for multiple programming languages and notebooks provides flexibility in implementing generation logic tailored to specific testing scenarios.

The synthetic data generation process follows a systematic approach designed for efficiency and scalability, as illustrated in the following diagram.
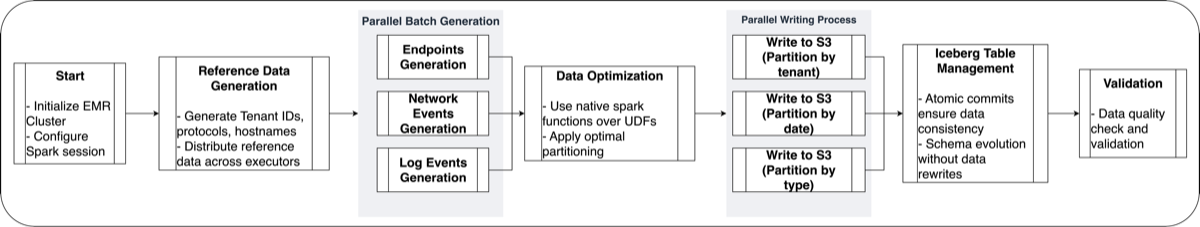
Synthetic data generation workflow showing the systematic process from configuration through data generation to storage

Although synthetic data generation isn’t a sensitive workload, it’s important to maintain robust security throughout the data generation process. Amazon EMR provides security features that align with organizational compliance requirements.

For comprehensive security guidance specific to Amazon EMR deployments, refer to Security in Amazon EMR. The solution follows the AWS Shared Responsibility Model, where AWS manages the security of the cloud infrastructure, and customers maintain responsibility for data security, access management, and compliance controls in the cloud. Specifically for synthetic data generation workloads, AWS manages the security of the underlying Amazon EMR infrastructure, network, and service operations, and customers implement appropriate security controls for their data generation pipelines. Consider the following key areas:

  • Data protection – Enable encryption at rest and in transit using Amazon EMR security configurations, including Amazon S3 encryption and TLS certificates for inter-node communication.
  • Network security – Deploy Amazon EMR clusters in private subnets with security groups following least privilege, and enable the Amazon EMR block public access feature.
  • Access control – Implement AWS Identity and Access Management (IAM) roles with least privilege for Amazon EMR service roles, Amazon Elastic Compute Cloud (Amazon EC2) instance profiles, and runtime roles to isolate job access. Fine-grained table-level and column-level permissions can be controlled using AWS Lake Formation. Additional authentication options are available using Kerberos and LDAP.

Optimize Faker for petabyte-scale data generation

When generating synthetic data at petabyte scale, using Faker’s implementations can quickly lead to performance bottlenecks. To overcome these limitations, adopt a combination of different optimization approaches instead of the default setup. Some of the approaches we adopted in this scenario are discussed in this section.

Faker instance pooling

The following code creates multiple Faker instances to avoid contention when generating data in parallel:

NUM_FAKER_INSTANCES = 10
faker_pool = [Faker() for _ in range(NUM_FAKER_INSTANCES)]

Consistent seed management

The following code provides reproducible data generation across distributed executors:

for faker in faker_pool:
    faker.seed_instance(42)  # For reproducibility
    random.seed(42)

Random access to Faker pool

The following code distributes load across multiple Faker instances to reduce contention:

faker = faker_pool[random.randint(0, NUM_FAKER_INSTANCES-1)]

Broadcast variables for reference data

The following code efficiently distributes reference data to all executors:

tenant_ids_broadcast = spark.sparkContext.broadcast(tenant_ids)
protocols_bc = spark.sparkContext.broadcast(protocols)

Batch generation of synthetic data

The following code generates fake data in batches rather than one-by-one:

return spark.range(1, num_endpoints + 1)
    .withColumn("hostname", random_hostname_udf())

ThreadPoolExecutor for parallel processing

The following code uses Python’s threading for parallel operations within executors:

def parallel_write_with_sync(dataframe_configs, max_workers=3):
    with ThreadPoolExecutor(max_workers=max_workers) as executor:
        # Parallel processing

Optimize Amazon EMR and Spark

When processing massive datasets with Spark on Amazon EMR, carefully tuning configurations can substantially enhance performance beyond the standard settings. In this section, we discuss ways to optimize the execution environment, so you can efficiently handle petabyte-scale workloads with synthetic data generation. By strategically using Spark’s advanced features and configuring Amazon EMR for your specific use case, you can improve throughput, reduce processing time, and maximize resource utilization.

Arrow configuration

The following code enables Apache Arrow for efficient data transfer between Python and JVM. The default value is false.

.config("spark.sql.execution.arrow.pyspark.enabled", "true")

Enable this configuration when your PySpark application frequently converts data between Python and JVM, especially for large DataFrames or when using Pandas operations. Keep this setting disabled for pure Spark SQL workloads or when memory is constrained.

This optimization is most effective in the following scenarios:

  • When processing large-scale datasets that require frequent conversion between Python and JVM.
  • In a PySpark application where large DataFrame operations and Pandas integration are needed.
  • With data science workloads that combine Python UDFs with Spark SQL operations.

Consider the following trade-offs:

  • Arrow maintains in-memory columnar format, resulting in increased memory consumption.
  • Not all data types are fully supported in older versions of Spark.
  • It might introduce overhead for very small datasets where conversion costs outweigh the benefits.

Adaptive query execution

The following code allows Spark to dynamically optimize query execution plans. The default value is true in Spark 3.2 and later, and false in earlier versions.

.config("spark.sql.adaptive.enabled", "true")

This optimization is generally recommended to keep enabled for most workloads. Consider disabling only when you have highly optimized, predictable queries where the adaptive overhead isn’t beneficial, or when troubleshooting query performance issues.

This optimization is most effective in the following scenarios:

  • Complex join operations with unknown or skewed data distributions.
  • Multi-stage queries where initial plans might be suboptimal.
  • When processing data with changing characteristics over time.

Consider the following trade-offs:

  • You may experience additional overhead during the query planning phase.
  • You might occasionally choose suboptimal plans for certain edge cases.

Parallelism configuration

The following code sets appropriate parallelism for distributed data processing based on the volume of data you’re generating. The default value for spark.default.parallelism is the total number of cores on all executor nodes or 2, whichever larger. The default value for spark.sql.shuffle.partitions is 200.

.config("spark.default.parallelism", 1000)
.config("spark.sql.shuffle.partitions", 1000)

Adjust this configuration when the default of 200 shuffle partitions creates too many small tasks (increase data volume) or too few large tasks (decrease for smaller datasets). Generally, aim for partition sizes of 100–200 MB. Modify default.parallelism when your RDD operations need different parallelism than the CPU-based default.

This optimization is most effective in the following scenarios:

  • When generating consistent volumes of synthetic data across multiple runs.
  • When you have predictable resource requirements.
  • When you need to precisely control executor utilization.

Consider the following trade-offs:

  • Static configuration might not adapt well to varying data volumes.
  • Too many partitions can lead to task scheduling overhead.
  • Too few partitions might cause memory pressure on executors.

Memory management

The following code optimizes memory allocation for execution and storage. The default value for spark.memory.fraction is 0.6, and for spark.memory.storageFraction is 0.5.

.config("spark.memory.fraction", 0.8)
.config("spark.memory.storageFraction", 0.3)

Increase memory.fraction from 0.6 to 0.8 when your workload is memory-intensive and you’re not using the JVM heap for other purposes. Adjust storageFraction based on your caching vs. execution memory needs. Decrease to 0.3 if you do minimal caching but have complex computations, and increase to 0.7 or higher for cache-heavy workloads.

This optimization is most effective in the following scenarios:

  • Workloads that are memory-intensive and need fine-grained control.
  • Workloads that balance between execution memory and cached data.
  • During synthetic data generation that has many interdependent fields.

Consider the following trade-offs:

  • Incorrect memory configuration can lead to frequent spills to disk or out-of-memory (OOM) errors.
  • You might need to change the configuration to suit different workload characteristics.
  • The settings must be monitored and tuned for optimal performance.

Limited Python UDF usage

The following code uses Spark’s built-in functions where possible instead of Python user-defined functions (UDFs). No additional configuration is needed. This is a coding practice.

.withColumn("risk_score", F.round(F.rand() * 9 + 1, 2).cast(DecimalType(3, 2)))

We recommend using Spark functions over Python UDFs when the same functionality can be achieved. Use Python UDFs only when complex business logic can’t be expressed using Spark’s built-in functions, or when integrating with specialized Python libraries.

This optimization is most effective in the following scenarios:

  • Simple transformations that can be performed using Spark functions.
  • High-throughput workloads where serialization overhead needs to be minimized.

Consider the following trade-offs:

  • This approach is less flexible compared to customer Python-based transformations or functions.
  • You might need to use complex expressions to accomplish certain data patterns.
  • There is a potential learning curve to familiarize yourself with Spark functions.

DataFrame caching

The following code caches frequently used DataFrames to avoid regenerating data. The default behavior doesn’t use caching. DataFrames are recomputed on each action.

endpoints_df = generate_endpoints().cache()

Use this optimization to cache DataFrames that are accessed multiple times in your application. Monitor memory usage and use MEMORY_AND_DISK storage level for large DataFrames. Uncache DataFrames when they’re no longer needed to free memory.

This optimization is most effective in the following scenarios:

  • When reusing reference data across multiple operations (can result in performance gains).
  • For workloads where the same data is processed on multiple occasions.

Consider the following trade-offs:

  • Too much caching might lead to memory process.
  • Planning is required to manage cache in environments where memory is scarce.

Optimal partitioning

By default, Spark determines partitioning based on input data and previous operations. The following code makes sure data is properly distributed across executors:

.repartition(20)

Use repartition() when you need to increase partitions for better parallelism or support even data distribution. Use coalesce() when reducing partitions to avoid small files. Generally, target 100–200 MB per partition for optimal performance.

This optimization is most effective in the following scenarios:

  • When controlling data distribution and avoiding data skew is very important.
  • Before executing an expensive operation that will benefit from balanced data distribution.
  • When optimizing downstream consumption use cases.

Consider the following trade-offs:

  • This option is more expensive than coalesce(). For large datasets, repartition() can lead to large shuffle.
  • The approach requires trial and experimentation to determine the optimal partition count.
  • There is no “one-size-fits-all” setting. Different applications or operations might gain performance with different partitioning.

Partition-aware writing

By default, data is written without partitioning. The following code organizes data for efficient storage and retrieval:

{"df": network_events_df, "name": "network_events", "partition_cols": ["tenant_id"]}

Partition data when you have predictable query patterns that filter on specific columns. Choose partition columns that are frequently used in WHERE clauses and have reasonable cardinality (avoid too many small partitions or too few large ones).

This optimization offers the following benefits:

  • Allows for highly parallel write operation across multiple executors.
  • Organizes the data that is close to real-world production data.
  • Allows for partition pruning when querying the data.

Consider the following trade-offs:

  • Excess partitioning or too fine-grained partitioning might result in small files.
  • It might result in data skew because of hot partitions.
  • You might encounter storage and metadata overhead because of excessive partitions.

Best practices

Through our journey from terabytes to petabytes, we’ve identified several best practices:

  • Begin with a modest dataset and incrementally scale, allowing for identification of bottlenecks at each stage.
  • Implement robust data validation checks to confirm synthetic data maintains expected properties at scale.
  • Regularly review and adjust Amazon EMR configurations, using Spot Instances and right-sizing clusters.
  • Develop parameterized job scripts that can adjust data volume, complexity, and cluster resources dynamically.
  • Design your synthetic data schema and generation logic to quickly accommodate new fields or changing distributions over time.

Conclusion

Our journey from terabytes to petabytes of synthetic data generation demonstrates how Amazon EMR, combined with Spark and Faker, can effectively address large-scale testing needs. The architecture we explored in this post scales to meet demanding data generation requirements while maintaining data quality and cost-efficiency.

We showed how starting with a solid foundation at terabyte scale, then gradually expanding through Amazon EMR managed services and Spot Instances, helps organizations build robust synthetic data pipelines. The combination of efficient data generation techniques, proper validation, and continuous monitoring provides reliable results at scale.

To begin implementing your own synthetic data generation system, start small, test thoroughly, and scale incrementally. For implementation guidance, refer to Generate production-grade synthetic data at petabyte-scale using Apache Spark and Faker on Amazon EMR.
About the authors

Anubhav Awasthi

Anubhav Awasthi

Anubhav is a Senior Big Data Specialist Solutions Architect at Amazon Web Services (AWS). He collaborates with customers to provide expert architectural guidance for implementing and optimizing analytics solutions using Amazon EMR, Amazon Athena, AWS Glue, and AWS Lake Formation.

Gagan Brahmi

Gagan Brahmi

Gagan is a Specialist Senior Solutions Architect at Amazon Web Services (AWS), focused on Data Analytics and AI/ML. With over 20 years in information technology, he partners with customers to solve complex AI/ML challenges by leveraging data and AI/ML platforms. Gagan helps customers architect scalable, high-performance solutions that utilize distributed data processing, real-time streaming technologies, and AI/ML services to drive business transformation through artificial intelligence and data-driven insights. When not designing cloud-native data and AI solutions, Gagan enjoys exploring new places with his family.

Jayaprakash Boreddy

Jayaprakash Boreddy

Jayaprakash is a Senior Solutions Architect at AWS. He works with ISV customers in designing and building highly scalable, flexible and resilient applications on AWS Cloud.

Sahil Thapar

Sahil Thapar

Sahil is a Principal Solutions Architect. He works with ISV customers to help them build highly available, scalable, and resilient applications on the AWS Cloud.

Regional routing for AWS access portals: Implementing custom vanity domains for IAM Identity Center

Post Syndicated from Georgi Baghdasaryan original https://aws.amazon.com/blogs/security/regional-routing-for-aws-access-portals-implementing-custom-vanity-domains-for-iam-identity-center/

AWS IAM Identity Center provides a web-based access portal that gives your workforce a single place to view their AWS accounts and applications. With the recent launch of IAM Identity Center multi-Region replication, customers can replicate their IAM Identity Center instance across multiple AWS Regions to improve resilience and reduce latency for a globally distributed workforce. As a result, users have a dedicated access portal URL in each Region where Identity Center is replicated, and where administrators need a consistent way to manage these portals to ensure that each user reaches the right one.

This post walks you through building a custom vanity domain (for example, aws.mycompany.com) that serves as a single, memorable entry point for access to IAM Identity Center through the AWS Management Console. The solution uses latency-based routing to automatically redirect users to their nearest healthy access portal endpoint and provides a mechanism to trigger failovers when a Regional Identity Center instance, or the broader AWS Region, is impaired. Because this solution operates outside of Identity Center—at the DNS and load balancer layer—users are transparently redirected to the appropriate Regional access portal URL. Note that the vanity domain itself will not appear in the browser’s address bar.

This guide is structured in three progressive phases: a single-Region redirect, multi-Region latency routing, and automatic health-based failover. You can adopt each phase independently, depending on your organization’s needs.

Note: While this guide focuses on IAM Identity Center access portal endpoints, the same approach using Amazon Route 53 latency-based routing, Application Load Balancer (ALB) redirects, and Amazon Application Recovery Controller (ARC) Region switch can be applied to build a custom vanity domain and intelligent routing layer for any other HTTP endpoint type.

Background

IAM Identity Center supports multiple access portal URL formats that resolve to the same web portal. The following table summarizes the supported formats in the standard AWS (classic) partition, along with their capabilities:

Format IPv4 Dual-stack Multi-Region* Example
https://{directoryId}.awsapps.com/start Yes No No https://d-1234567890.awsapps.com/start
https://{alias}.awsapps.com/start Yes No No https://mycompany.awsapps.com/start
https://{idcInstanceId}.{region}.portal.amazonaws.com Yes No Yes https://ssoins-1234567890.us-west-2.portal.amazonaws.com
https://{idcInstanceId}.portal.{region}.app.aws ★ Yes Yes Yes https://ssoins-1234567890.portal.us-west-2.app.aws

* Each Regional URL resolves only to its own Region’s portal instance and doesn’t fail over to another Region. Multi-Region here means the URL format is available in every Region where IAM Identity Center is replicated. To route users across Regions dynamically, use the vanity domain approach described in this post.

Note: The ★ highlighted row (https://{idcInstanceId}.portal.{region}.app.aws) is the recommended URL format. It supports both dual-stack (IPv4 and IPv6) and IAM Identity Center multi-Region replication. The awsapps.com formats aren’t always available in newer Regions and don’t support multi-Region capabilities. In additional replicated Regions, the custom alias isn’t supported, and the awsapps.com parent domain isn’t available.

Working with multiple Regional endpoints

As you expand your IAM Identity Center footprint through multi-Region replication, each replicated Region provides a dedicated access portal URL—directing your users to the low-latency entry point closest to their location. A user connecting from Europe and one connecting from Asia Pacific each benefit from their respective Regional endpoint. To deliver the best experience, organizations need a consistent, centrally managed way to direct users to the correct Regional destination; there are a few common approaches you can use to achieve this.

Customers typically start with a single Regional endpoint, which is straightforward to configure, but users in distant Regions experience higher latency, and a Regional incident can affect all users regardless of location. Others maintain per-Region bookmarks or configuration, which gives each user population the right endpoint but requires ongoing IT coordination and clear communication to users.

Custom vanity domains give you full control over DNS routing, health checks, and failover of your access portal connections; all behind a single, brand-aligned domain name (for example, aws.mycompany.com) that users access. A vanity domain makes this start URL memorable and consistent for users, regardless of the underlying IAM Identity Center configuration – a single address to remember and share, compared to maintaining a separate bookmark for each Regional endpoint or managing a growing list of application tiles in your external identity provider. The rest of this guide walks you through how to deploy this solution step by step.

Solution overview

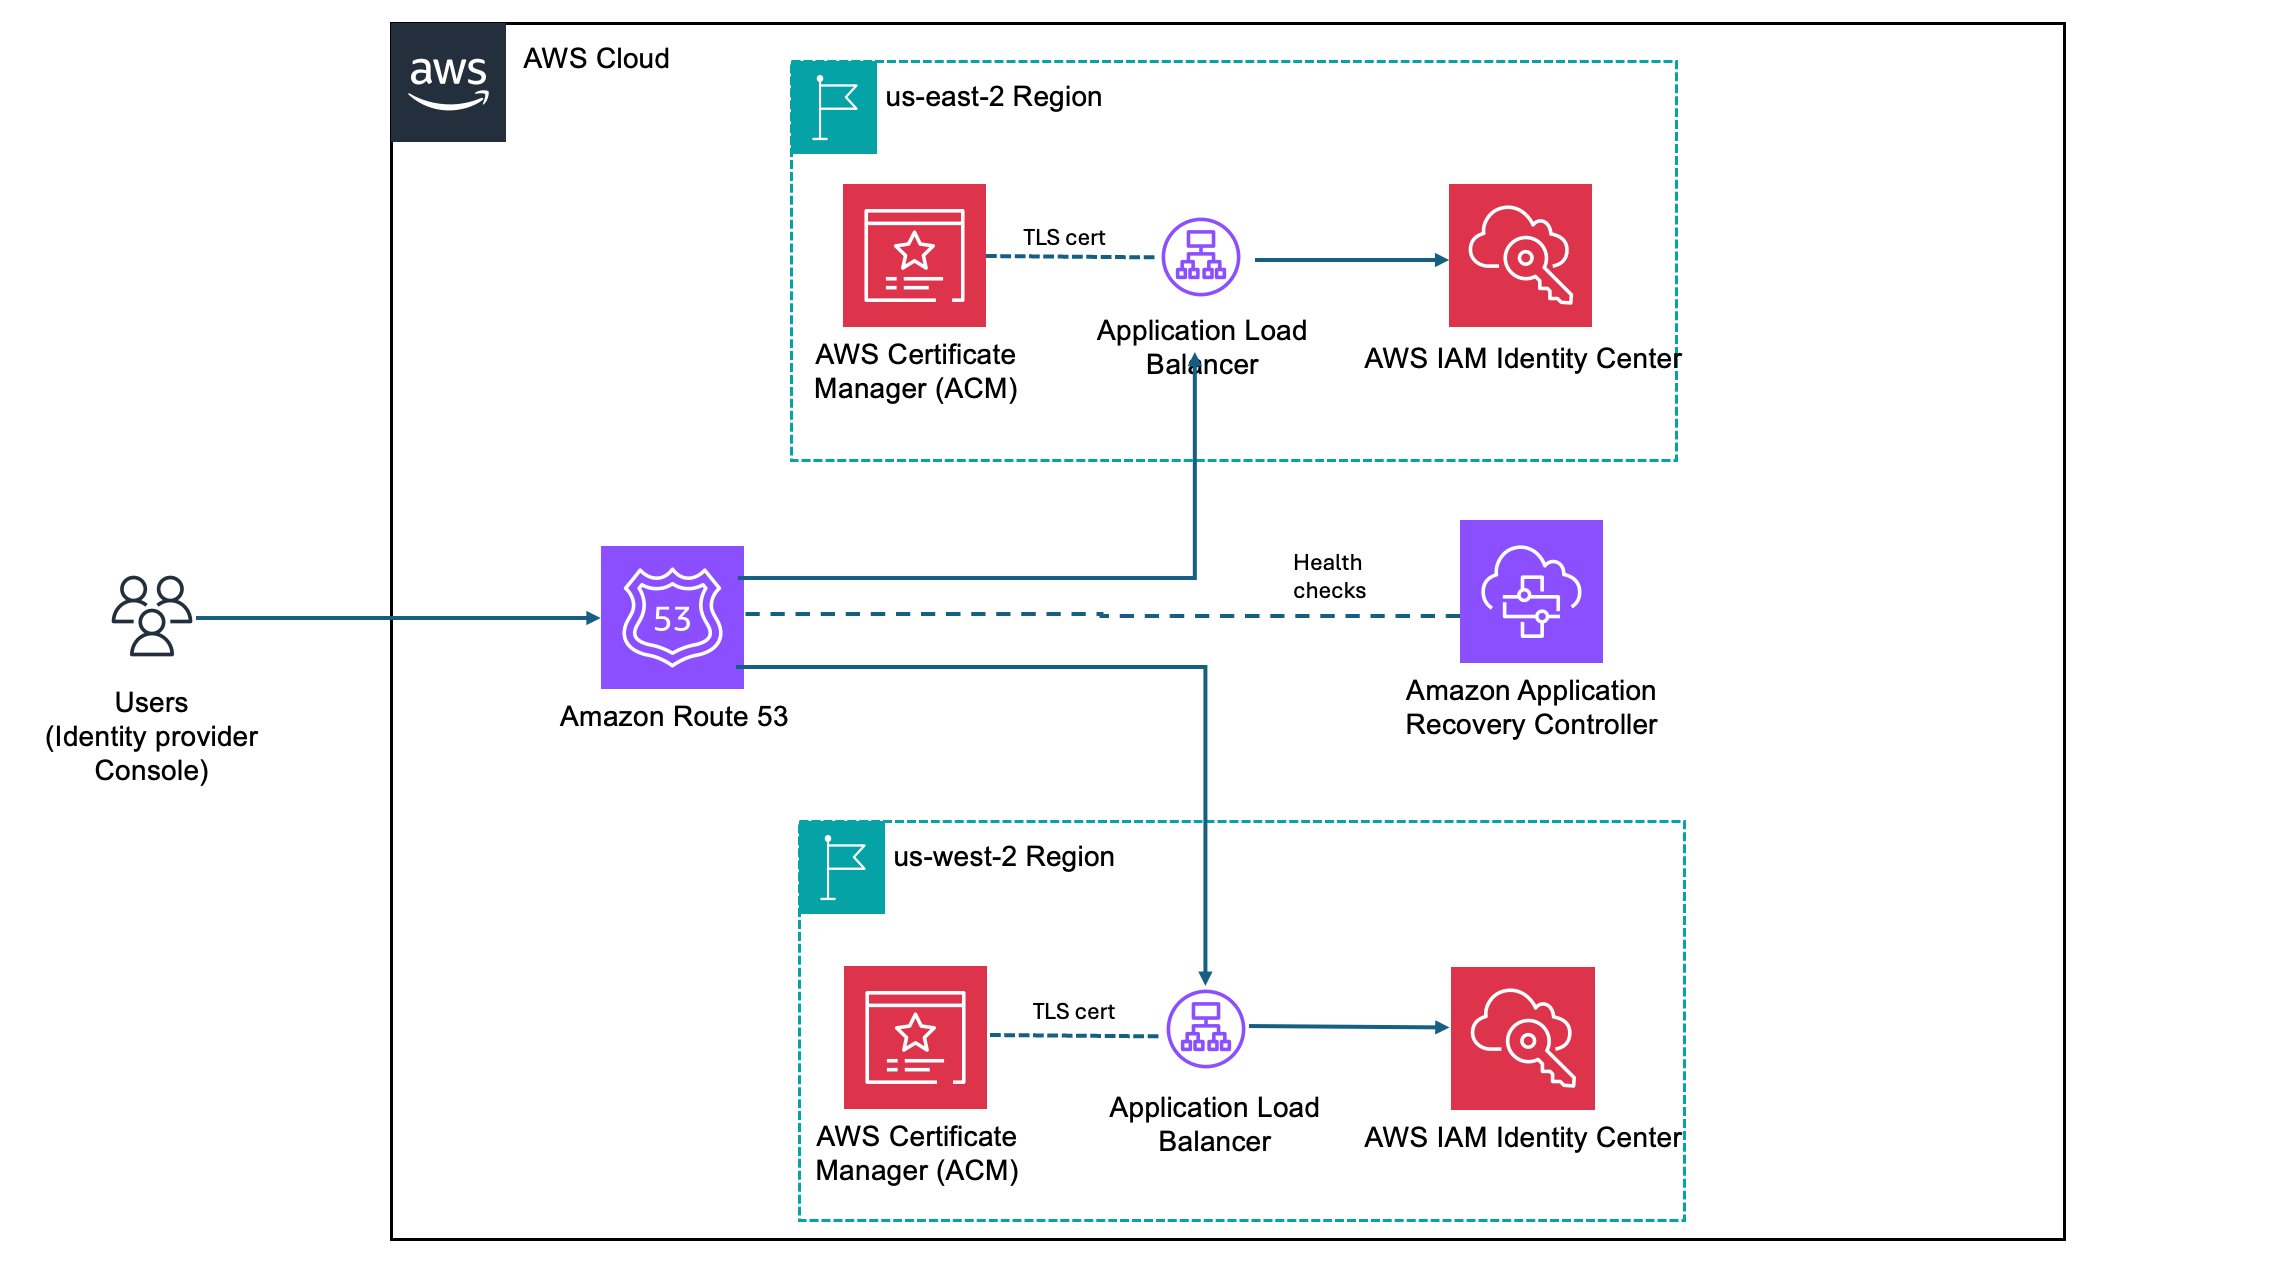
The solution builds a lightweight routing and redirect layer in front of the IAM Identity Center access portal Regional endpoints. The architecture has the following components:

  • AWS IAM Identity Center – Your existing Identity Center instance
  • Amazon Route 53 – Manages your vanity domain’s hosted zone, latency-based routing policy, and health checks
  • AWS Certificate Manager (ACM) – Issues and automatically renews TLS certificates for your vanity domain in each Region
  • Application Load Balancer (ALB) – Handles HTTP and HTTPS traffic, issuing 302 redirects to the appropriate Regional access portal endpoint
  • Amazon Application Recovery Controller (ARC) Region switch – Orchestrates Regional failovers by controlling Route 53 health check states, so traffic is automatically shifted away from an unhealthy Region

This guide is structured in three progressive phases. You can adopt each phase incrementally based on your needs:

  • Phase 1: Sets up the vanity domain with a redirect to a single Regional access portal endpoint. Suitable for organizations with a single-Region Identity Center deployment.
  • Phase 2: Extends Phase 1 across multiple Regions with latency-based routing, so users are automatically directed to the nearest Regional endpoint. Requires IAM Identity Center multi-Region replication.
  • Phase 3: Adds an ARC Region switch for managed Regional failover. Without Phase 3, a Regional impairment requires manual DNS updates to redirect traffic. ARC automates this with rehearsable, controlled failover plans.

Figure 1: Solution architecture for custom vanity domain routing with IAM Identity Center.

When a user navigates to aws.mycompany.com, the following happens:

  1. Route 53 evaluates the latency records and routes traffic to the ALB in the lowest-latency healthy Region.
  2. The ALB terminates TLS using an ACM-managed certificate and issues a 302 redirect to the corresponding Regional Identity Center access portal URL.
  3. The user’s browser follows the redirect and loads the access portal directly. Subsequent authentication traffic flows between the browser and AWS—the ALB isn’t in the path.

If you’ve implemented Phase 3, ARC controls Route 53 health check states for each Region. With this configuration, you can stop routing traffic to any Region considered unhealthy.

Prerequisites

Before you begin to build the solution, ensure you have the following in place:

  1. An existing top-level domain (TLD) (for example, mycompany.com).
  2. An AWS IAM Identity Center organization instance configured.
  3. For Phases 2 and 3, you need IAM Identity Center multi-Region replication configured with at least two Regions. See Setting up IAM Identity Center multi-Region replication for instructions.
  4. AWS Identity and Access Management (IAM) permissions on a dedicated networking or shared services account in your organization to manage Route 53, ACM, Amazon Elastic Compute Cloud (Amazon EC2), ALB (phase 1 and 2), and ARC (phase 3).

Phase 1: Redirect to a single predefined access portal endpoint

In this phase, you create the foundational infrastructure: a Route 53 hosted zone, an ACM-managed TLS certificate, and an internet-facing ALB that issues a 302 redirect to your Regional access portal URL. By the end, users who navigate to aws.mycompany.com will be seamlessly redirected to your Identity Center portal.

Create a Route 53 hosted zone for your vanity domain

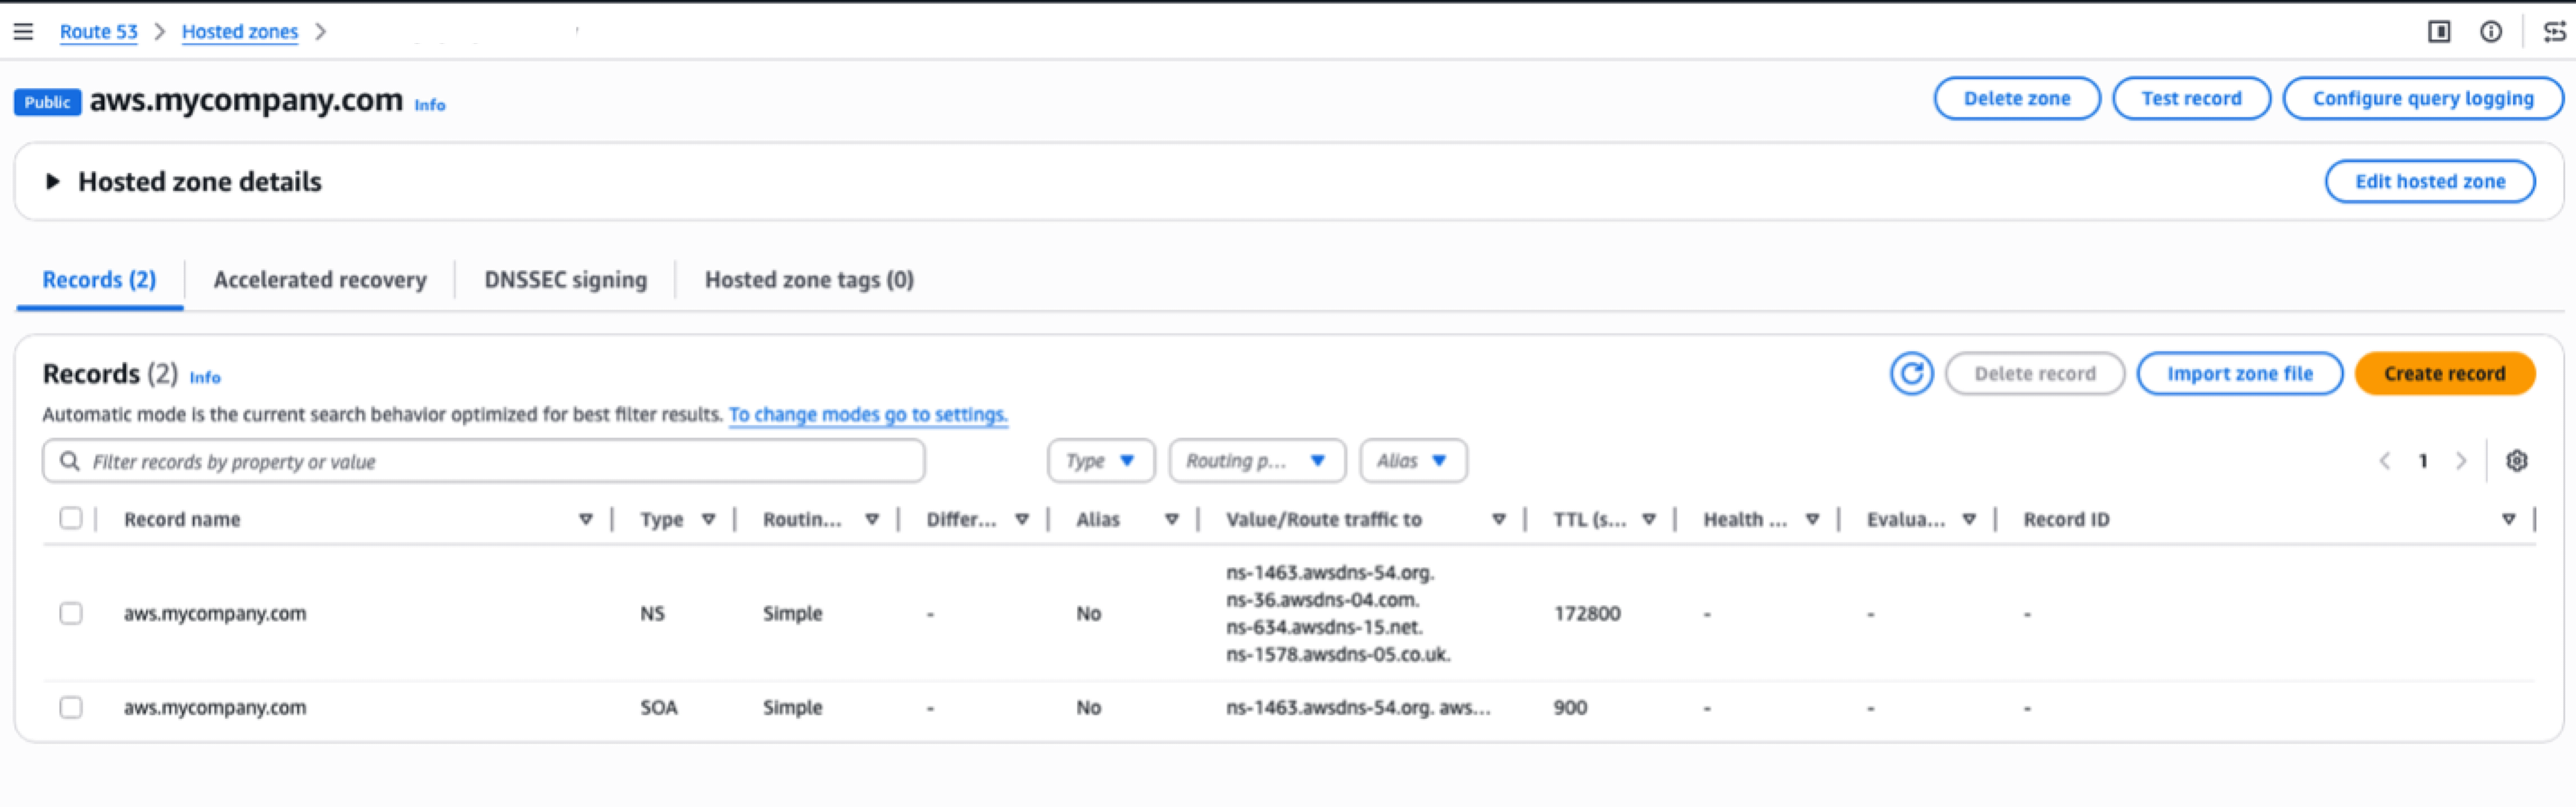
The hosted zone holds the DNS records that control how aws.mycompany.com resolves. If your top-level domain (mycompany.com) is already registered in Route 53, you create a subdomain hosted zone. If it’s registered with another registrar, you create a public hosted zone and configure name server (NS) delegation manually.

  1. In the AWS Management Console, navigate to Route 53 and choose Hosted zones, then Create hosted zone.
  2. Enter your vanity domain in the Domain name field (for example, aws.mycompany.com).
  3. Select Public hosted zone as the type, then choose Create hosted zone.
  4. Note the four NS records that Route 53 creates for the new hosted zone. You will need these in the next step.

Figure 2: Route 53 hosted zone details

Delegate your subdomain from the parent domain

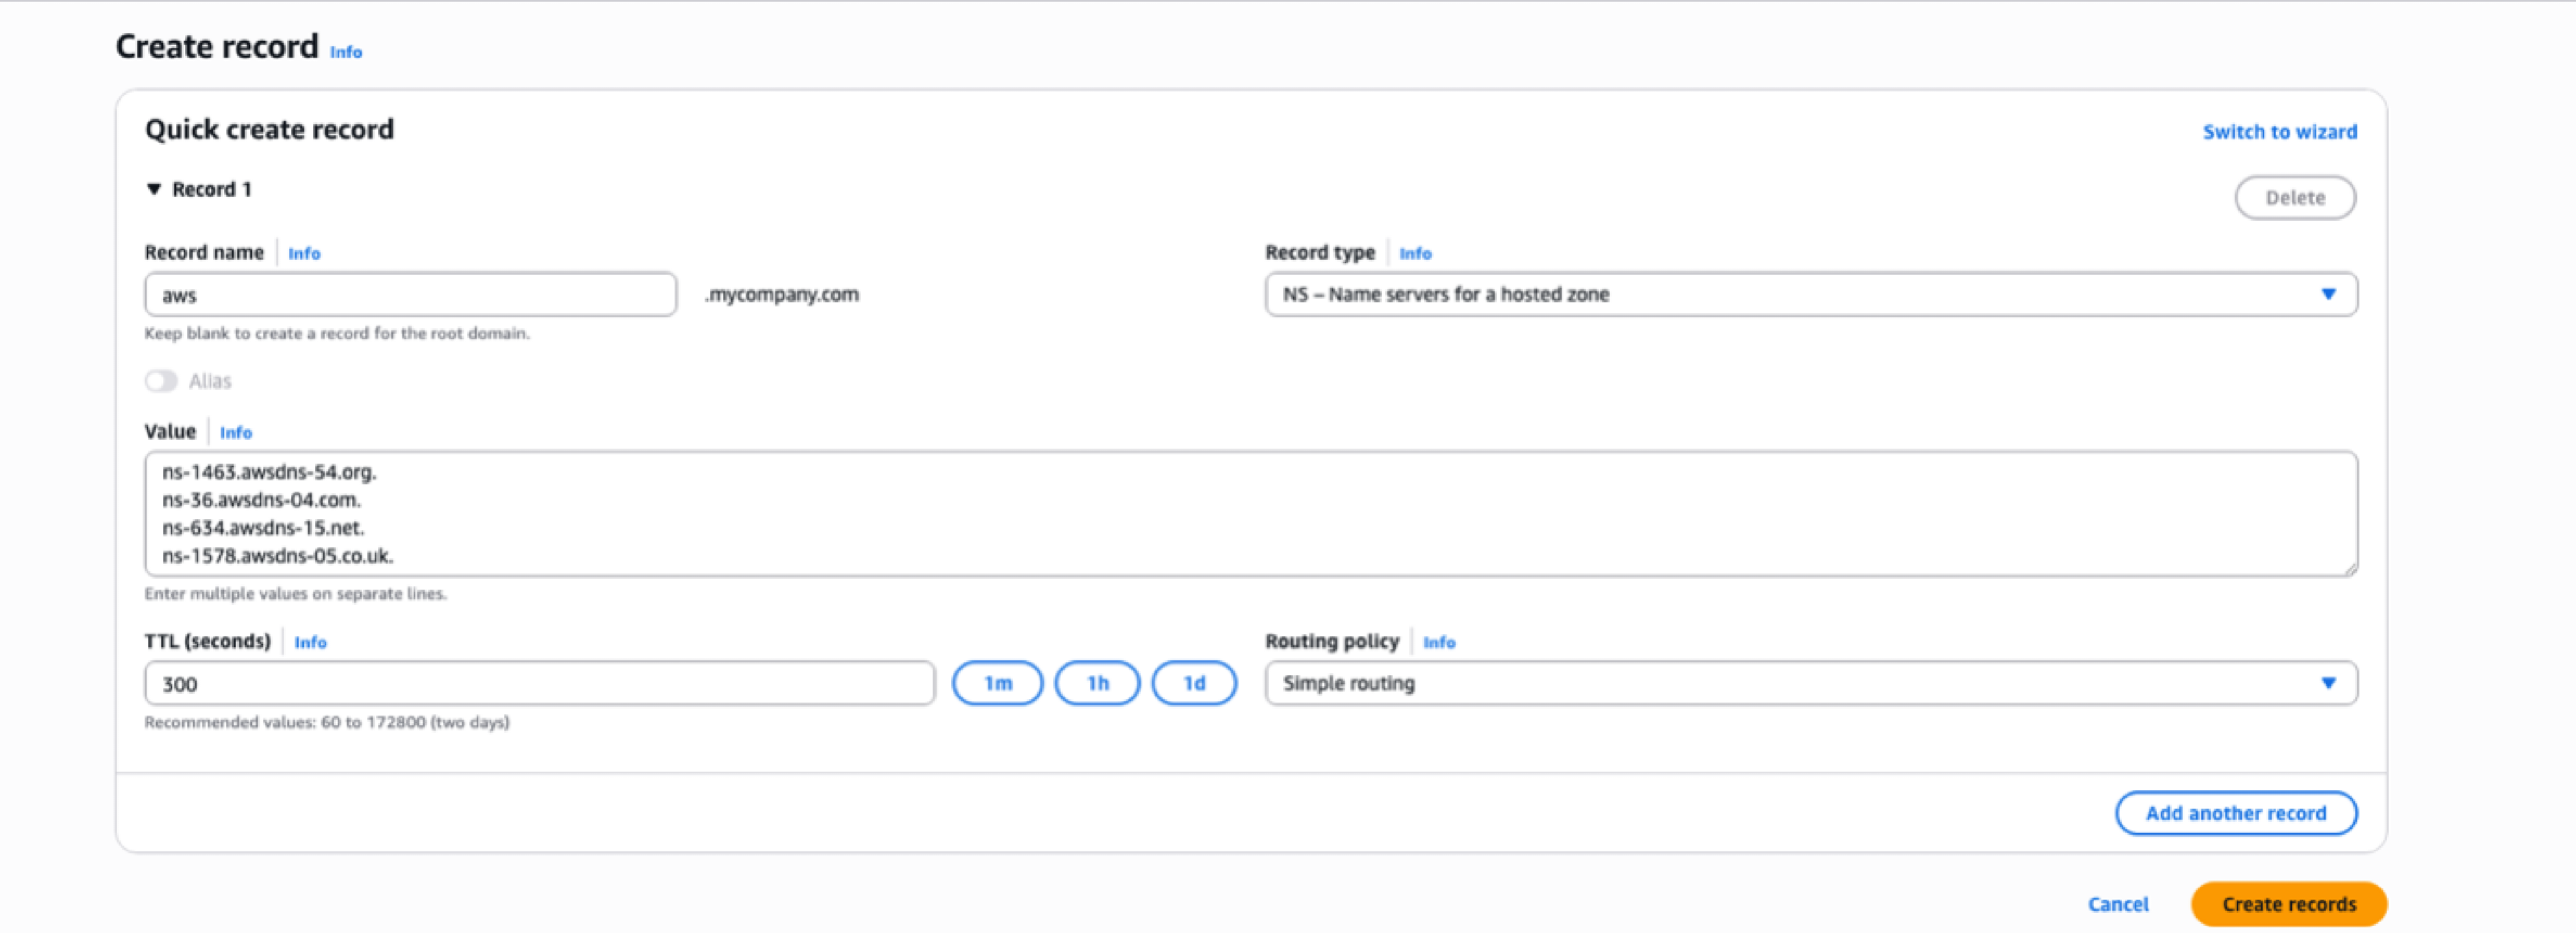
To make Route 53 authoritative for aws.mycompany.com, you must add an NS record in the parent zone (mycompany.com) pointing to the name servers of the new hosted zone.

  • If mycompany.com is hosted in Route 53: Open the mycompany.com hosted zone, choose Create record, set the record name to aws, the type to NS, and paste the four NS values from the previous step. Choose Create records.
  • If mycompany.com is hosted elsewhere: Sign in to your registrar’s DNS management console and add an NS record for aws.mycompany.com using the four name server values from the previous step.

Note: DNS propagation for NS delegation can take up to 48 hours, though it typically completes within a few minutes for Route 53-to-Route 53 delegation.

Figure 3: Create a NS record type to delegate your subdomain from the parent domain

Request an ACM certificate

Your ALB requires a TLS certificate for aws.mycompany.com to serve HTTPS traffic. ACM provides free public certificates with automatic renewal.

  1. Go to the Certificate Manager console in the primary Region of IAM Identity Center (for example, us-east-2) and choose Request a certificate.
  2. Select Request a public certificate and choose Next.
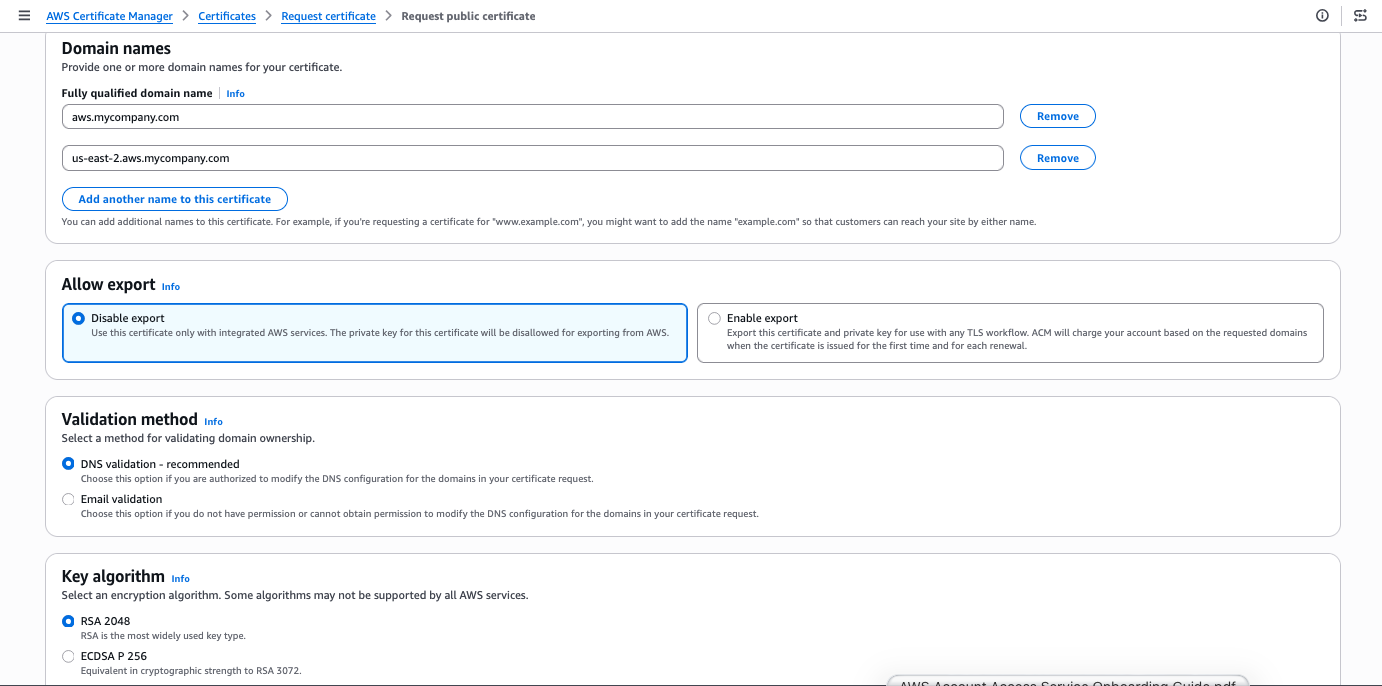
  3. Enter your domain name (for example, aws.mycompany.com). Choose Add another name to this certificate and enter your Regional sub-domain (for example, us-east-2.aws.mycompany.com).
  4. Leave other options as defaults (Disable export, DNS validation – recommended, and key algorithm – RSA 2048) and choose Request.
  5. In the certificate details page, choose Create records in Route 53. ACM will automatically add the validation CNAME records to your hosted zone. The certificate status changes to Issued within a few minutes.

Figure 4: Request an ACM certificate for your domain

Create a security group for Identity Center ALB

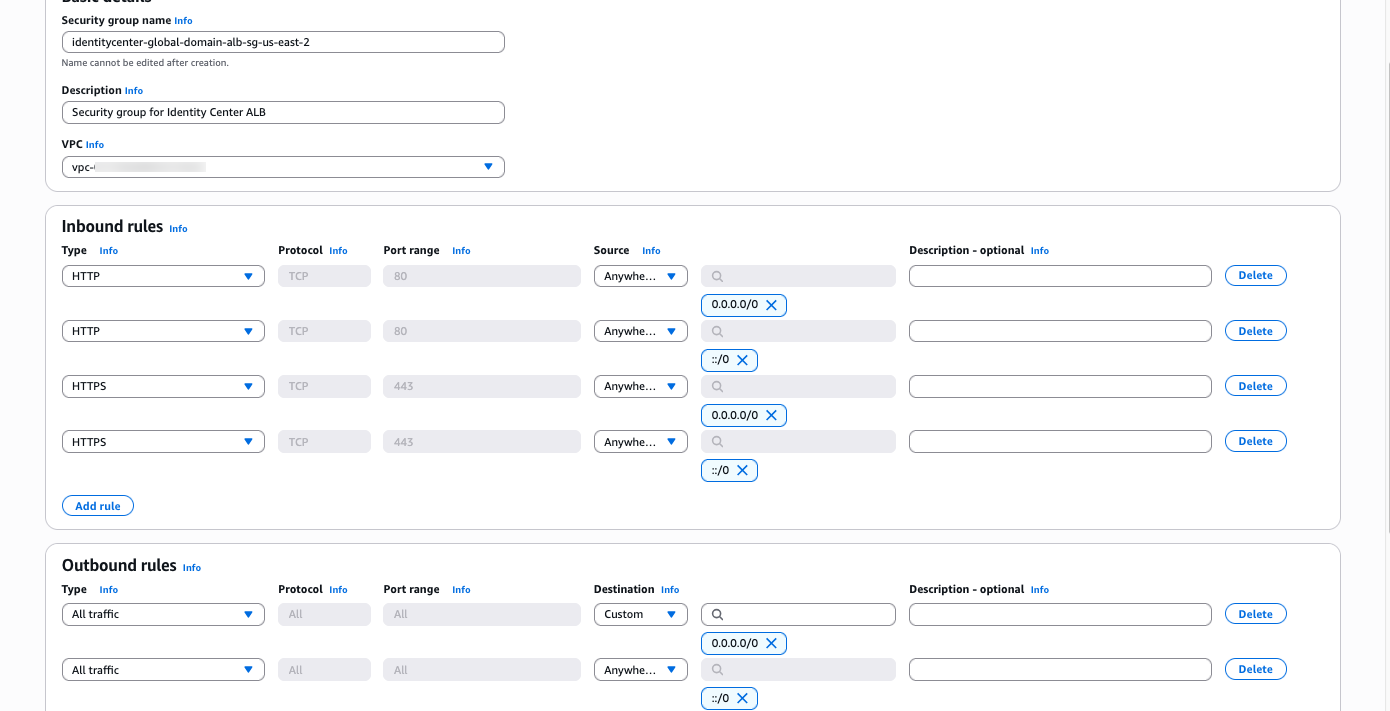
The security group needs to allow inbound HTTP and HTTPS traffic for both IPv4 and IPv6 from the public internet to make the load balancer reachable.

  1. Go to the Amazon EC2 console, navigate to Security Groups, and choose Create security group.
  2. Enter a Name (for example, identitycenter-global-domain-alb-sg-us-east-2) and Description. Add four rules by choosing Add Rule under Inbound Rules.
    1. Set Type to HTTP, and Source to Anywhere-IPv4 (0.0.0.0/0) and to Anywhere-IPv6 (::/0).
    2. Set Type to HTTPS, and Source to Anywhere-IPv4 (0.0.0.0/0) and to Anywhere-IPv6 (::/0).
  3. Choose Add Rule under Outbound Rules and set Type to All traffic and Source to Anywhere-IPv6 (::/0).
  4. Choose Create security group.

Figure 5: ALB security group rules

Create an ALB with an HTTP and HTTPS redirect rule

The ALB is the component that performs the actual redirect to your IAM Identity Center access portal URL. The ALB listener accepts HTTPS requests on port 443 and responds with a 302 redirect to the appropriate Regional Identity Center access portal endpoint.

  1. Go to the Amazon EC2 console, navigate to Load Balancers, and choose Create load balancer. Select Application Load Balancer.
  2. Enter a name for your ALB (for example, identitycenter-redirect-alb).
  3. Configure basic settings: Set the scheme to Internet-facing, IP address type to Dualstack (or IPv4 if IPv6 isn’t supported by your virtual private cloud (VPC)), and select at least two Availability Zones. Ensure that the load balancer is operating in a VPC and subnets that are internet-facing.
  4. Under Security Groups choose the Security Group created in the previous step.
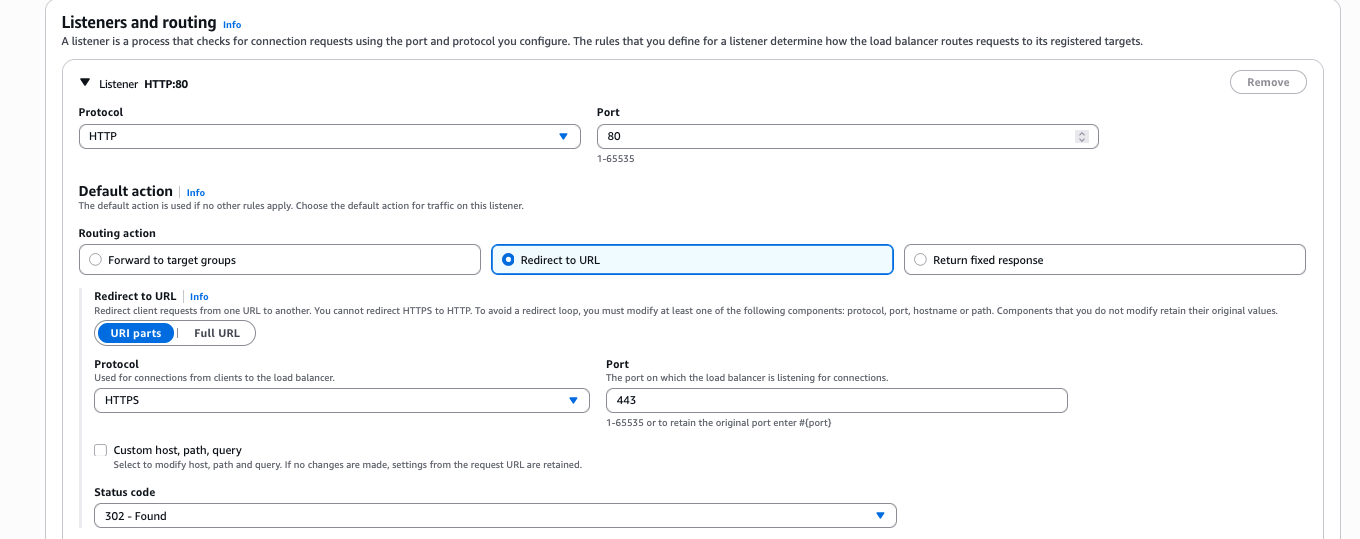
  5. Configure an HTTP listener: Add a listener on port 80 (HTTP) with Redirect to URL option. Choose URL parts and set Protocol to HTTPS, Port to 443, and status code to 302 (Found).

    Figure 6: Add an HTTP listener during ALB creation

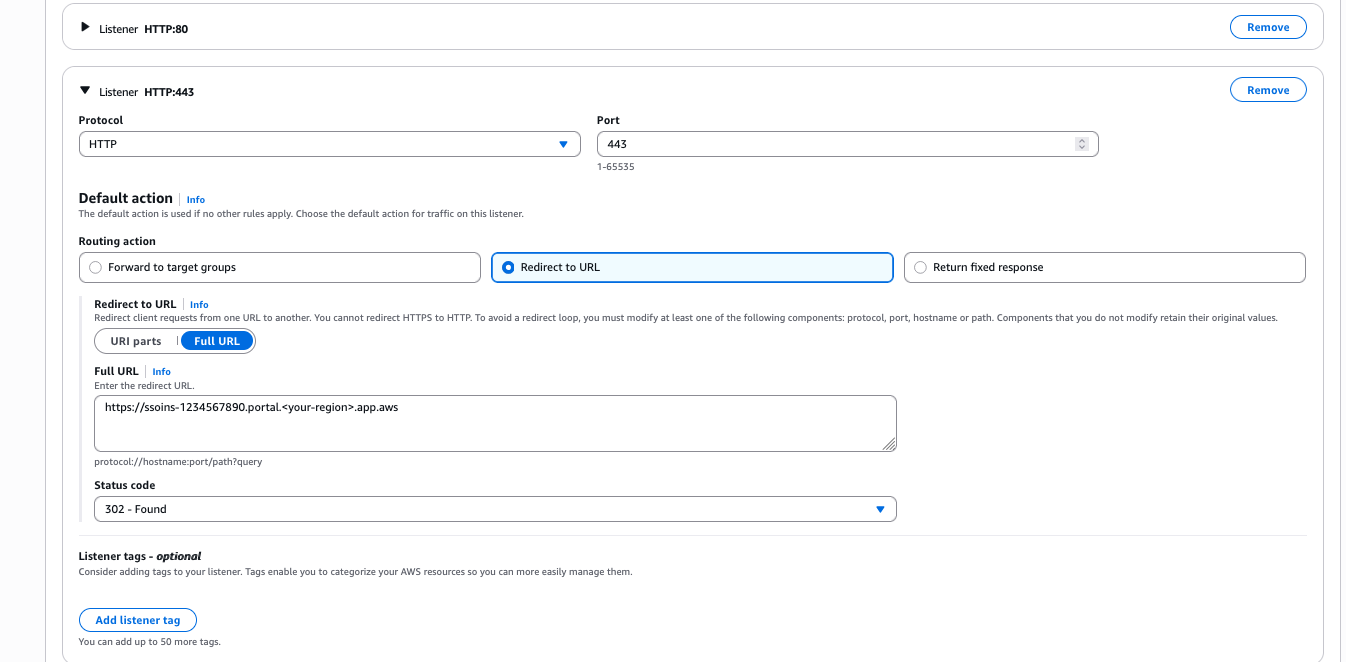
  6. Configure an HTTPS listener: Add a listener on port 443 (HTTPS) with No pre-routing action (default) and Redirect to URL options. Choose Full URL and set the URL to your Regional Identity Center access portal endpoint (For example, https://ssoins-1234567890.portal.<your-region>.app.aws, for this blog the region is us-east-1). Set status code to 302 (Found).

    Figure 7: Add an HTTPS listener

  7. Under Default SSL/TLS certificate, select the ACM certificate you created in Step 3.

    Note: Make sure to select 302 – Found as the Status code. Selecting 301 – Permanently moved will result in browser caching the redirect URL which will prevent failovers from working correctly until the cache expires.

Create Regional Route 53 records pointing to your ALB

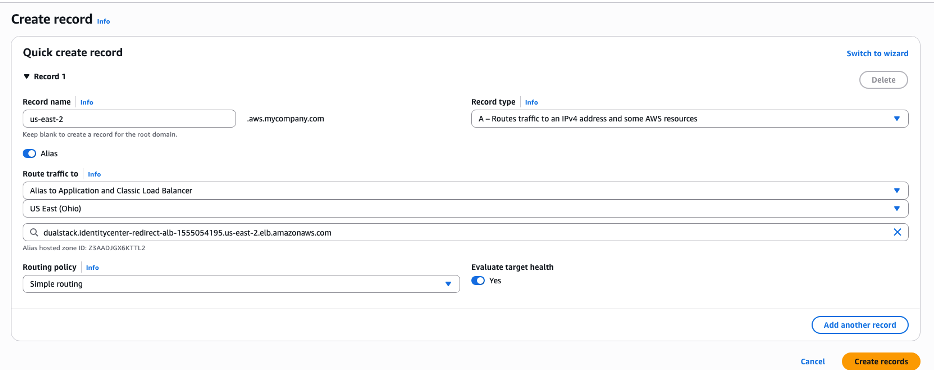
Create a DNS record in your hosted zone that resolves <your-region>.aws.mycompany.com to your ALB.

  1. Open your Route 53 hosted zone for aws.mycompany.com and choose Create record.
  2. Set the record name to the AWS Region name (For example: us-east-2) and the record type to A.
  3. Toggle Alias and in the drop down menu Route traffic to, select the alias target to Alias to Application and Classic Load Balancer, select your Region (For example:us-east-2), and select your ALB from the dropdown list.
  4. Leave routing policy as Simple routing, and select the Region (For example:us-east-2) and choose Create records.
  5. Repeat steps 1 through 4 to create AAAA record types.

Figure 8: Route 53 record with simple routing policy

Add latency-based routing configurations

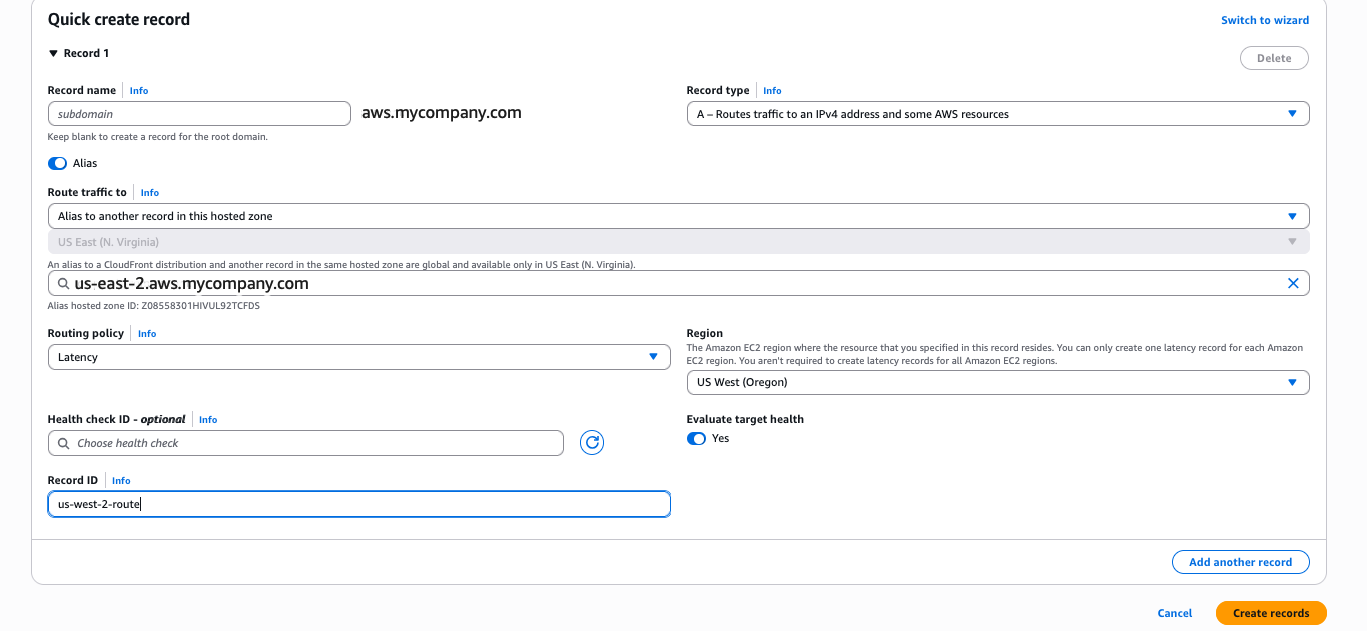
Finally, create a DNS record in your hosted zone that resolves aws.mycompany.com to your Regional Route 53 record.

  1. Open your Route 53 hosted zone for aws.mycompany.com and choose Create record.
  2. Keep the subdomain name for this record as empty, so aws.mycompany.com is the fully qualified record and set the record type to A.
  3. Enable alias: Set the Route traffic to Alias to another record in this hosted zone, and select the hosted zone you created earlier (us-east-2.aws.mycompany.com).
  4. Set Routing Policy to Latency and select the corresponding Region (us-east-2 in this example).
  5. Add a clear name for the Record ID, such as us-east-2--ipv4 as a differentiator and choose Create records.
  6. Repeat the steps 1 through 5 to create AAAA record types with us-east-2--ipv6 as the record ID.
Figure 9: Route 53 record with latency-based routing

Figure 9: Route 53 record with latency-based routing

Test the configuration by navigating to https://aws.mycompany.com in a browser. You should be redirected to your Identity Center access portal. You can also validate using:
curl -I https://aws.mycompany.com

Expected response:

HTTP/2 302

location: https://ssoins-1234567890.portal.<your-region>.app.aws

Tip: To deploy Phase 1 automatically, download the CloudFormation template from the Deploying with CloudFormation section below.

Phase 2: Automatically route to the nearest Regional access portal endpoint

Phase 2 extends the solution to support IAM Identity Center multi-Region replication by deploying an ALB in each replicated Region and configuring Route 53 latency-based routing. Users are automatically directed to the access portal in the Region that has the lowest network latency from their location, which matches the active-active behavior of the Identity Center access portal itself.

Request ACM certificates in each additional Region

Repeat the steps from Request an ACM Certificate for each additional Region (for example, us-west-2) where you’ve replicated IAM Identity Center.

Create a security group and an ALB in each additional Region

Repeat the steps from Create a security group for Identity Center ALB and Create an ALB with an HTTP and HTTPS redirect rule in each additional Region. In each ALB’s redirect rule, set the target URL to the access portal endpoint for that specific Region. For example:

  • us-east-2 ALB redirects to https://ssoins-1234567890.portal.us-east-2.app.aws
  • us-west-2 ALB redirects to https://ssoins-1234567890.portal.us.west-2.app.aws

Create Regional and latency Route 53 records for the additional Region

For each additional Region where you’ve deployed an ALB and replicated Identity Center, create Regional and latency A and AAAA records as outlined in Create Regional Route 53 records pointing to your ALB and Add latency-based routing configurations.

Tip: To deploy Phase 2 automatically, download the CloudFormation template from the following Deploying with CloudFormation section.

Phase 3: Regional failover using ARC Region switch

Phase 3 introduces Amazon Application Recovery Controller (ARC) Region switch, a fully managed capability that you can use to plan, practice, and orchestrate Regional failovers with confidence. ARC Region switch vends Route 53 health checks directly as part of a Region switch plan. You attach these generated health checks to your Route 53 latency records, and ARC controls their healthy or unhealthy state during plan execution. You can further extend the solution to include custom automation triggered by Amazon CloudWatch alarms or synthetic canaries to update routing control state.

We recommend creating your ARC Region switch plan in the primary Region of your IAM Identity Center for ease of discovery.

Create an active-active instance of ARC Region switch plan

Create an ARC Region switch plan that will orchestrate failovers between your IAM Identity Center Regions and auto-generate the Route 53 health checks you will reference in the next step.

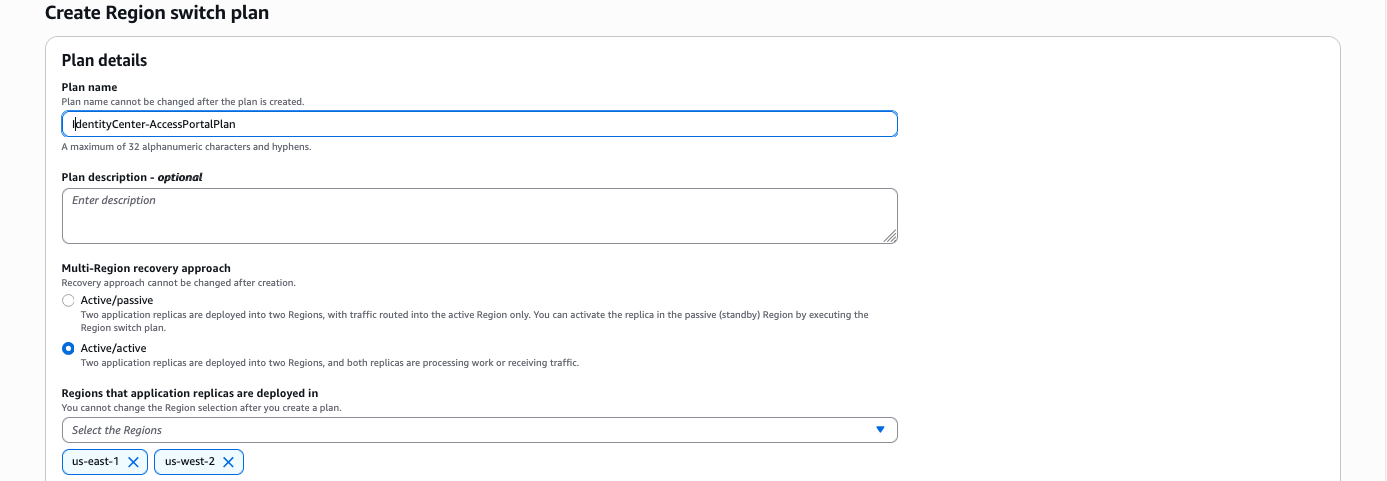
  1. Open the Application Recovery Controller console and choose Region switch in the navigation pane. Select Create Region Switch Plan.
  2. Enter a Plan name (for example, idc-access-portal-failover) and an optional description. Choose Active/Active for Multi-Region recovery approach. Select the Regions where IAM Identity Center is replicated ,including the primary Region.
  3. In the Execution Permission section, enter the Amazon Resource Name (ARN) of the IAM role that ARC will use to update Route 53 health check states during plan execution. If you don’t have an existing role, choose Create a new role to have ARC create one automatically. See AWS Managed Policy: AmazonApplicationRecoveryControllerRegionSwitchPlanExecutionPolicy for information about required permissions.
  4. Choose Create Plan and proceed to Build workflows. Enter optional descriptions and choose Save and continue.

    Figure 10: Region switch plan

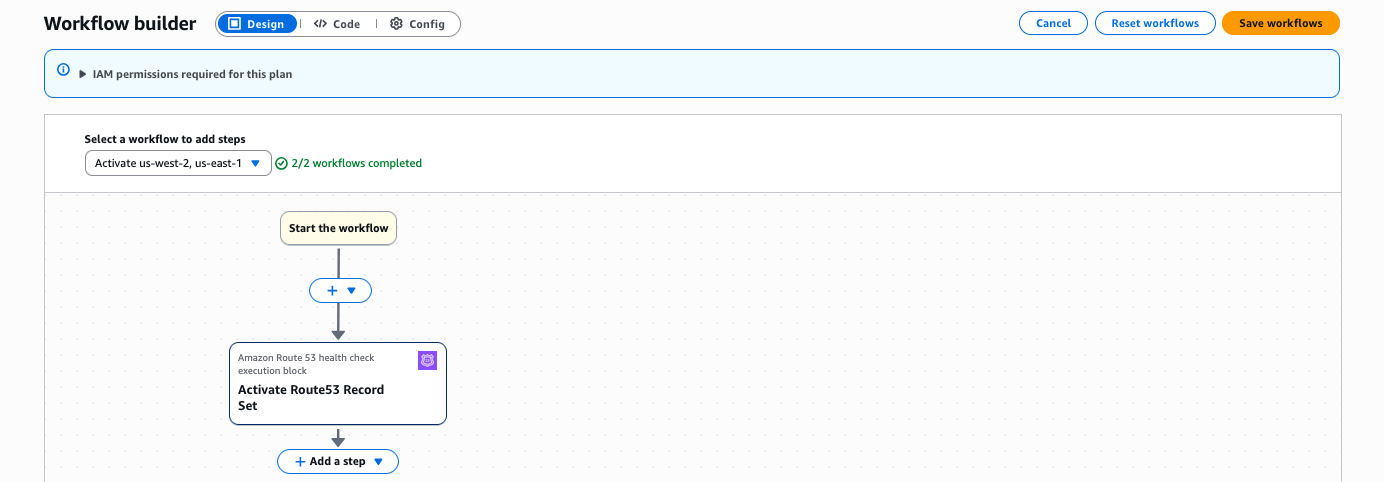
  5. Set the Workflow type to Activate and set the Region to the corresponding Region (us-east-2 or us-west-2). Within each workflow, choose Add step/Run in Sequence. Choose an execution block to Amazon Route 53 health check execution blog under Networking.
  6. Choose Add and edit. Enter a Step name (for example, Activate Route53 Record Set).
  7. Set the Hosted zone to the hosted zone ID for your aws.mycompany.com domain, and set the Record name to aws.mycompany.com.
  8. Expand Record set identifiers. Choose Add record set identifier and enter a unique identifier for the record set (for example, us-east-2--ipv4 and us-east2--ipv6) and select your Region. Add two record set identifiers (A and AAAA records) for each of your Regions.
  9. Choose Save step.
  10. Repeat steps 5 and 6 for Deactivate and choose Save the plan.

    Figure 11: Workflow builder

  11. Choose Save workflows.
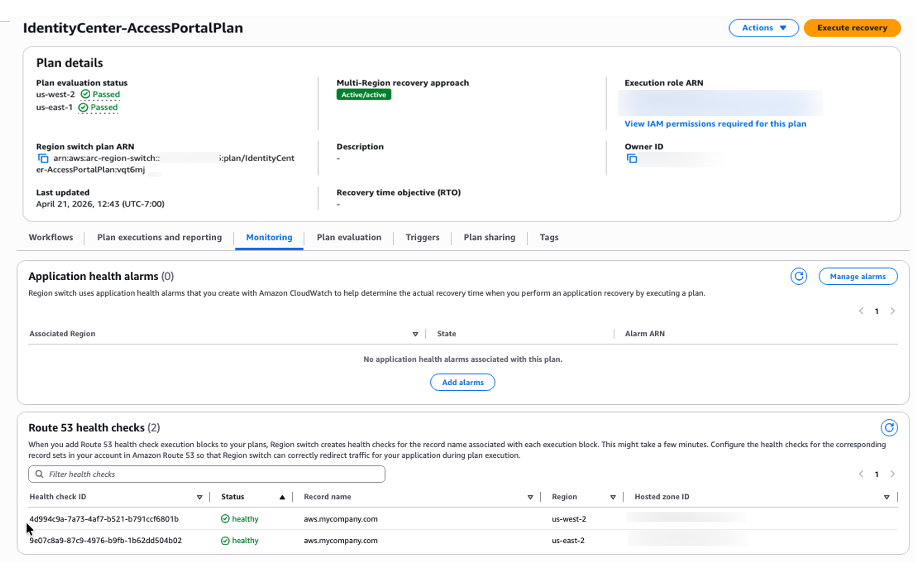
  12. Select the newly created plan and choose the Monitoring tab. Note the IDs of the health checks created.

    Figure 12: IAM Identity Center access portal plan

Update Route 53 record sets to reference ARC-managed health checks

Associate the ARC-generated health check IDs with the latency-based A and AAAA records you created in Phase 1 and 2. Route 53 uses these health checks—which are now controlled by ARC—to determine which Regions are eligible for DNS resolution. Route 53 still uses latency to choose from the healthy Regions.

    1. Go to the Route 53 console and choose Hosted zones.
    2. Select the hosted zone for aws.mycompany.com.
    3. Find the latency-based A record for us-east-2 that you created in Phase 2, and choose Edit record.
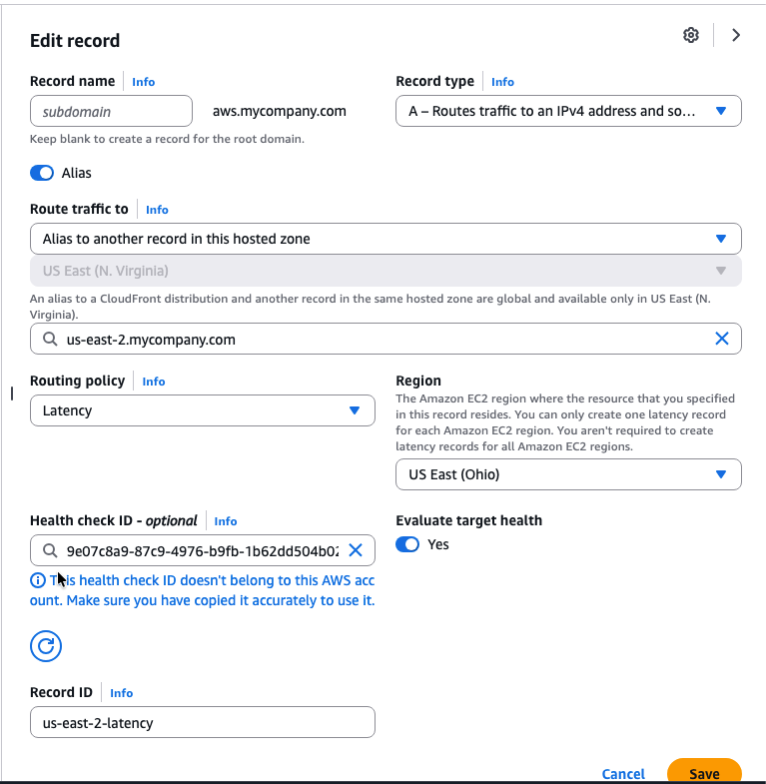
    4. In the Health check section, enable Associate with a health check. In the Health check ID dropdown, select the ARC-generated health check for us-east-2 that you noted at the end of the preceding procedure. Note: Ignore the warning This health check ID doesn’t belong to this AWS account. Make sure you have copied it accurately to use it.
    5. Choose Save changes.
    6. Repeat steps 3, 4, and 5 for A and AAAA records for each of your IAM Identity Center Regions.

Figure 13: Update Route53 record sets

Validate the setup by performing a failover

Validate the end-to-end configuration by executing a controlled failover. Because latency-based routing will always resolve aws.mycompany.com to us-east-2 for users in the primary geography, deactivating us-east-2 is the most direct way to confirm that Route 53 correctly fails over to us-west-2.

    1. Before executing the failover, confirm that aws.mycompany.com is resolving to the us-east-2:
      curl -I https://aws.mycompany.com
      Expected: A record pointing to the us-east-2 access portal URL (for example, https://ssoins-1234567890.portal.us-east-2.app.aws:443/).
    2. Go to the Amazon Application Recovery Controller console. In the left navigation pane, choose Region switch.
    3. Select your Region switch plan (idc-access-portal-failover) to open the plan details page.
    4. Choose Execute recovery.
    5. On the Execute plan page, select us-east-2 as the Region to fail out of.
    6. Select the Deactivate action and choose Start execution. ARC sets the us-east-2 health check to unhealthy. Route 53 stops resolving aws.mycompany.com to the us-east-2 ALB and routes traffic to us-west-2 instead.
    7. After a few seconds, confirm the failover has taken effect:
      curl -I https://aws.mycompany.com
      Expected: 302 redirect to the us-west-2 IAM Identity Center access portal URL
    8. To fail back, choose Execute plan again. Select us-east-2, select the Activate action and choose Start execution. ARC marks the us-east-2 health check healthy and Route 53 resumes routing traffic to that Region.

Tip: To deploy Phase 3 automatically, download the CloudFormation template from the Deploying with CloudFormation section that follows.

Deploying with CloudFormation

As an alternative to the manual console steps described previously, we provide CloudFormation templates that you can download and deploy for each phase. Each template is self-contained and parameterized, so you only need to provide your environment-specific values (such as your vanity domain name, VPC, and subnet IDs). Download the templates from the following links:

To deploy a template, navigate to the AWS CloudFormation console, choose Create stack, select Upload a template file, and upload the downloaded YAML file. Follow the prompts to provide parameter values and create the stack. For Phase 2, deploy the template once in each additional Region.

Deploy all phases with a single scrip

As an alternative to deploying each CloudFormation template individually, you can use the provided deploy.sh bash script to deploy all three phases in sequence. The script automates stack creation across your primary and additional Region. To get started, download the deployment package, then unzip the file into a local directory:

wget https://aws-security-blog-content.s3.us-east-1.amazonaws.com/public/sample/3536-regional-routing-for-aws-access-portals/Vanity-domains-cfn.zip
unzip  Vanity-domains-cfn.zip
cd Vanity-domains-cfn

Before running the script, open the deploy.sh file and update the following required parameters with your environment-specific values:

  • TLD – Your top-level domain (for example, mycompany.com)
  • TLD_HOSTED_ZONE_ID – The Route 53 hosted zone ID for your top-level domain
  • IDC_SUBDOMAIN – The Identity Center subdomain name (for example, aws)
  • IDC_INSTANCE_ID – Your IAM Identity Center instance ID (for example, ssoins-1234567890)
  • PRIMARY_REGION – The primary Region for your Identity Center instance (for example, us-east-2)
  • ADDITIONAL_REGIONS – The additional Region for multi-Region replication (for example, us-west-2)

After updating the configuration, run the deployment script:

./deploy.sh

The script deploys Phase 1 (single-Region redirect), Phase 2 (multi-Region latency-based routing), and Phase 3 (ARC Region switch failover) in order. Monitor the terminal output for stack creation progress and any errors.

After completing the setup, you can integrate the vanity URL (for example, aws.mycompany.com) directly into your identity provider, such as Okta or Microsoft Entra ID, as a bookmark application or a chiclet URL. By configuring the vanity URL as the bookmark target, users who launch the application from their identity provider dashboard are always redirected to the nearest IAM Identity Center access portal endpoint through latency-based routing. If a Regional impairment occurs and a failover is necessary, administrators can execute an ARC Region switch to deactivate the impaired Region, and users will automatically be redirected to the active Identity Center endpoint without any change to the bookmark URL or end-user experience.

Conclusion

In this post, you learned how to build a custom vanity domain for an AWS IAM Identity Center access portal using Amazon Route 53, AWS Certificate Manager, Application Load Balancer, and an Amazon Application Recovery Controller (ARC) Region switch. The three-phase approach lets you start with a single-Region redirect, progressively add latency-based routing as your IAM Identity Center footprint grows with multi-Region replication, and then introduce an ARC Region switch to gain fully managed, rehearsable Regional failover.

For more information about IAM Identity Center multi-Region replication, see the IAM Identity Center User Guide. For more resilience patterns, visit the AWS Architecture Blog posts about Resilience. If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Resources


Georgi Baghdasaryan

Georgi Baghdasaryan

Georgi is a Principal Engineer at Amazon Web Services, where he builds identity systems that help organizations securely manage access and authentication at scale. His broader focus is on reliable, high-impact infrastructure that enables customers to operate confidently in the cloud. Outside of work, Georgi enjoys experimenting with new matcha latte recipes and going on long bike rides.

Sowjanya Rajavaram

Sowjanya Rajavaram

Sowjanya is a Sr Solutions Architect who specializes in Identity and Security in AWS. She works on helping customers of all sizes solve their identity and access management problems. She enjoys traveling and exploring new cultures and food.

Author

Laura Reith

Laura is an Identity Solutions Architect at AWS, where she thrives on helping customers overcome security and identity challenges. In her free time, she enjoys wreck diving and traveling around the world.

Automating post-quantum cryptography readiness using AWS Config

Post Syndicated from Pravin Nair original https://aws.amazon.com/blogs/security/automating-post-quantum-cryptography-readiness-using-aws-config/

Migrating your TLS endpoints to Post-quantum cryptography (PQC) starts with understanding your current TLS endpoint inventory and posture. This post introduces the PQC Readiness Scanner — an automated tool that inventories your Application Load Balancer (ALB), Network Load Balancer (NLB), and Amazon API Gateway endpoints and continuously monitors their TLS configurations for PQC readiness. The scanner classifies each endpoint into a three-tier framework that helps prioritize and plan PQC migration.

As quantum computing advances, you need to migrate to quantum-resistant cryptography to protect your data long-term. The PQC Readiness Scanner helps you identify which endpoints to migrate first and tracks your progress across accounts. For web traffic, PQC key exchange algorithms are negotiated only within TLS 1.3. This means quantum-resistant connections require endpoints that support TLS 1.3 and PQC key exchange.

Under the AWS Shared Responsibility Model, AWS secures the infrastructure and enables PQC support across its services. Customers are responsible for configuring their resources to use PQC-capable TLS policies. For AWS-terminated TLS connections—such as those on Application Load Balancer (ALB), Network Load Balancer (NLB), Amazon API Gateway, and Amazon CloudFront—customers choose the security policy (an AWS-managed configuration defining supported TLS protocol versions and cipher suites for a listener) that determines TLS version and cipher suite, key exchange, and authentication algorithm support.

The automated PQC Readiness Scanner for AWS-terminated TLS endpoints is built using AWS Config conformance packs. A conformance pack is a collection of AWS Config rules and remediation actions that can be deployed as a single entity in an account and a Region or across an organization in AWS Organizations.

Solution overview

The PQC Readiness Scanner deploys AWS Config rules using a conformance pack to evaluate the security policy on each endpoint. Based on the evaluation, each resource is classified into a three-tier readiness framework that prioritizes migration actions needed to achieve PQ-ready TLS.

The PQC Readiness Scanner performs two checks per resource:

  1. Does the endpoint use a PQ-ready security policy?
  2. Does the endpoint support legacy TLS 1.0 or 1.1?

Each check returns COMPLIANT or NON_COMPLIANT status with specific policy recommendations.

PQC requires endpoints to support TLS 1.3 and use PQC key exchange algorithms. The three-tier framework helps you interpret findings and prioritize fixes. The goal is to have TLS 1.3 with PQC key exchange enabled on the endpoints. However, achieving this requires maintaining backward compatibility with clients.

Tier

Readiness level

TLS protocols

PQC status

Migration priority

Tier 1

PQ-ready (strongest posture)

TLS 1.3 only with PQC key exchange

PQ-ready

None

Tier 2

PQ-ready (backward compatible)

TLS 1.2 and 1.3 with PQC key exchange

PQ-ready

Low

Tier 3

Not PQ-ready

No PQC key exchange

Not PQ-ready

High

How to prioritize your migrations

  • Tier 1 represents the strongest security using only TLS 1.3 with PQC key exchange. These resources already meet the target state.
  • Tier 2 represents a backward-compatible PQ-ready configuration. Endpoints support both TLS 1.2 and TLS 1.3, with PQC key exchange negotiated on TLS 1.3 connections. Migration priority is low because these resources already provide quantum-resistant protection for clients that support TLS 1.3, while maintaining TLS 1.2 compatibility for legacy clients. Migrate to Tier 1 when client-side analysis confirms that the connecting clients support TLS 1.3 with PQC key exchange.
  • Tier 3 covers resources that aren’t PQ-ready. This includes endpoints without TLS 1.3 support, endpoints with TLS 1.3 but without PQC key exchange policies. These resources require immediate attention.

Assessment scope

The scanner evaluates the following AWS edge services that terminate TLS connections on behalf of your applications.

  • Edge services:
    • Application Load Balancer (ALB), Network Load Balancer (NLB) listeners with HTTPS, TLS, and TCP SSL protocols are evaluated.
    • API Gateway REST APIs are evaluated for AWS Regional and private endpoints along with API Gateway HTTP APIs (v2) and WebSocket APIs (v2).
  • Excluded edge services:
    • CloudFront distributions are excluded from the PQC readiness scope because TLS 1.3 with hybrid post-quantum key exchange is automatically enabled across existing CloudFront TLS security policies for viewer-to-edge connections. No customer action is required for inbound (viewer-facing) PQC on CloudFront.
  • Recommended approach for Classic load balancer:
    • For Classic Load Balancers, AWS recommends migrating to ALB or NLB. Classic Load Balancers don’t support TLS 1.3 or PQC key exchange and can’t be made PQ-ready.

How the solution works

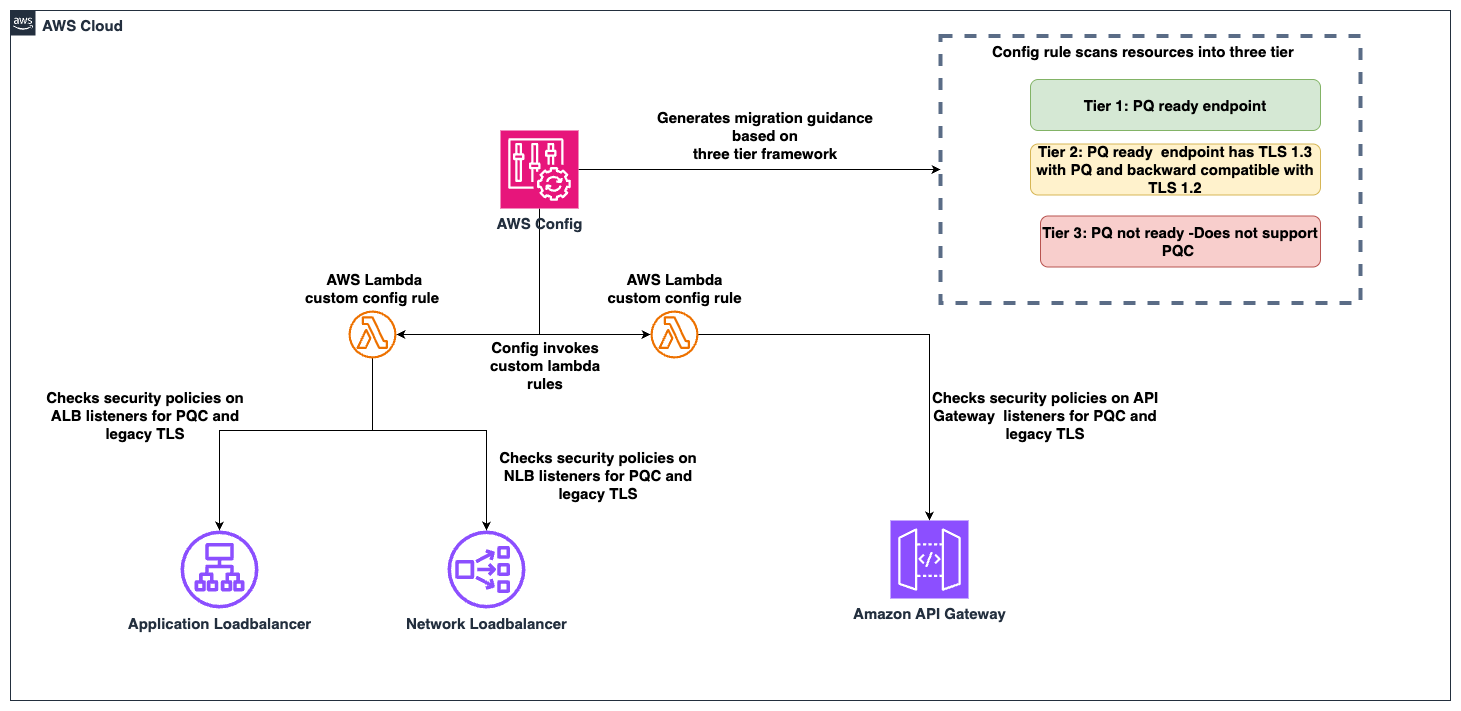
AWS Config enables continuous monitoring and evaluation. Conformance packs enable organization-wide deployment. AWS Lambda is a serverless compute service that runs code to perform security policy evaluation based on the AWS Config rules. AWS Serverless Application Model (AWS SAM) is an open source framework used for deploying the AWS Lambda functions.

Figure 1: PQC readiness solution architecture

Figure 1: PQC readiness solution architecture

The PQC Readiness Scanner conformance pack implements four custom AWS Config rules powered by two Lambda functions:

Rule

What it checks

Non-compliant result

ELB PQ-ready

Load balancer listeners use security policies that support TLS 1.3 with PQC key exchange algorithms

Policy doesn’t include PQC support, the resource is marked with a recommended upgrade policy

ELB legacy TLS

Load balancer listeners allow TLS 1.0 or 1.1 connections

Legacy protocols are configured, the resource is flagged.

API Gateway PQ-ready

API Gateway endpoints use security policies that support TLS 1.3 with PQC key exchange algorithms

Policy doesn’t include PQC support, the resource is marked with a recommended upgrade policy

API Gateway legacy TLS

API Gateway endpoints allow TLS 1.0 or 1.1

Legacy protocols are configured, the resource is flagged.

Prerequisites

Before deploying the solution, you need:

  • AWS Command Line Interface (AWS CLI) configured with appropriate permissions
    aws configure
    aws sts get-caller-identity  # Verify

  • Python 3.12 installed. The Lambda runtime requires this version.
    python3 --version  # Should show 3.12.x

  • AWS SAM CLI installed (Installation Guide)
    pip install aws-sam-cli
    
    # Verify
    sam --version

  • AWS Config enabled in your target AWS Region.
    • Configure it to record (This step is not needed if your accounts are recording all resources by default)
      • AWS::ElasticLoadBalancingV2::LoadBalancer
      • AWS::ApiGateway::RestApi
      • AWS::ApiGatewayV2::Api resource types.
    • Enable via AWS Config Console → Recorder → Recording Strategy → Select specific resource types (Follow the steps in manual setup for AWS Config recording strategy for specific resource types)

Steps to deploy the PQC Readiness Scanner

Deploy the PQC Readiness Config Scanner in three phases. Complete deployment commands and configuration details are available in the GitHub repository. The Lambda functions must be deployed first because the conformance pack references their ARNs as parameters. See the GitHub repository for details.

Deploy to single account:

  1. Clone and Build:
    git clone https://github.com/aws-samples/sample-PQC-Readiness-using-AWS-Config.git
    
    cd sample-PQC-Readiness-using-AWS-Config/installation
    
    sam build

  2. Deploy to One or More Regions:
    # Make script executable (first time only)
    chmod +x deploy-per-regions.sh
    
    # Deploy to a single region
    ./deploy-per-regions.sh us-east-1
    
    # Deploy to multiple regions
    ./deploy-per-regions.sh us-east-1 us-west-2 eu-west-1

    Type y and continue if you have enabled AWS Config recording for these resources or its by default recording all resources.

    Figure 2: Type y and continue if you have enabled AWS Config recording for these resources or its by default recording all resources.

  3. The script automatically:
    • Deploys Lambda functions via SAM
    • Deploys conformance pack (creates Config rules)
    • Verifies deployment success
    • Provides clear status messages

The deployment creates two Lambda functions that perform PQ-ready and legacy TLS checks. It provisions IAM roles with least-privilege permissions for ELB, ALB, NLB, and API Gateway describe operations. Lambda permissions allow AWS Config to invoke the functions.

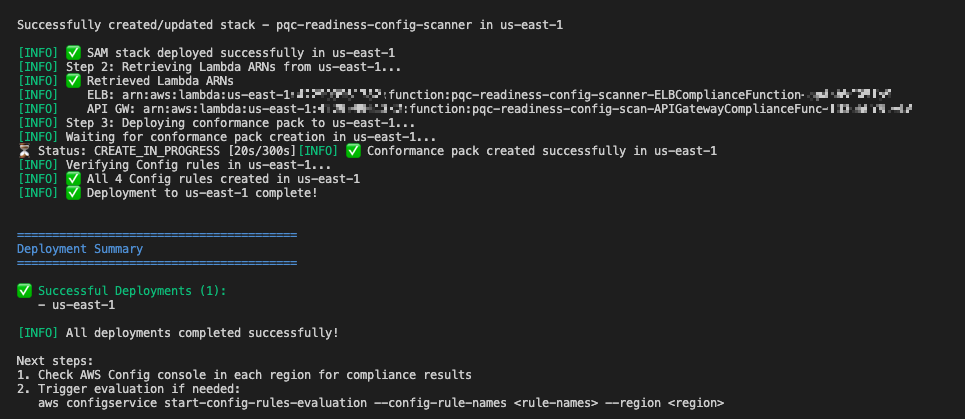
Example screen-print of how a successful deployment looks like.

Figure 3: Example screen-print of what a successful deployment looks like.

Multi-account deployment (Organizations):

For organization-wide deployment across multiple AWS accounts, use CloudFormation StackSets to deploy Lambda functions to each account.

Important Constraint: AWS Config CUSTOM_LAMBDA rules require the Lambda function to exist in the same account as the Config rule. You cannot use a centralized Lambda in one account to evaluate resources in other accounts.

Prerequisite: Shared S3 Bucket

Before packaging, create an S3 bucket accessible by each target account in your organization. This bucket will host the Lambda deployment artifacts that CloudFormation StackSets pulls into each member account.

# Create the shared S3 bucket (run from management/central account)
aws s3 mb s3://<your-org-shared-bucket> --region us-east-1

Grant read access to the target accounts using one of the following options:

aws s3api put-bucket-policy \
  --bucket <your-org-shared-bucket> \
  --policy '{
    "Statement": [
      {
        "Sid": "BucketOwnerFullAccess",
        "Effect": "Allow",
        "Principal": {
          "AWS": "arn:aws:iam::<bucket-owner-account-id>:root"
        },
        "Action": "s3:*",
        "Resource": [
          "arn:aws:s3:::<your-org-shared-bucket>",
          "arn:aws:s3:::<your-org-shared-bucket>/*"
        ]
      },
      {
        "Sid": "CrossAccountReadAccess",
        "Effect": "Allow",
        "Principal": {
          "AWS": [
            "arn:aws:iam::<account-id-1>:root",
            "arn:aws:iam::<account-id-2>:root"
          ]
        },
        "Action": ["s3:GetObject", "s3:ListBucket"],
        "Resource": [
          "arn:aws:s3:::<your-org-shared-bucket>",
          "arn:aws:s3:::<your-org-shared-bucket>/*"
        ]
      }
    ]
  }'

Replace <account IDs> with the AWS account IDs where StackSets will deploy the Lambda functions.

Note: The bucket must be in the same region as the StackSet deployment regions. For multi-region deployments, create one bucket per region and run sam package separately for each.

Step 1: Build and Upload Lambda Packages to S3

Run the packaging script from the installation/ directory:

cd installation

# Make script executable (first time only)
chmod +x deploy-stacksets.sh

# Build, package, upload to S3, and generate resolved template
./deploy-stacksets.sh <your-org-shared-bucket>

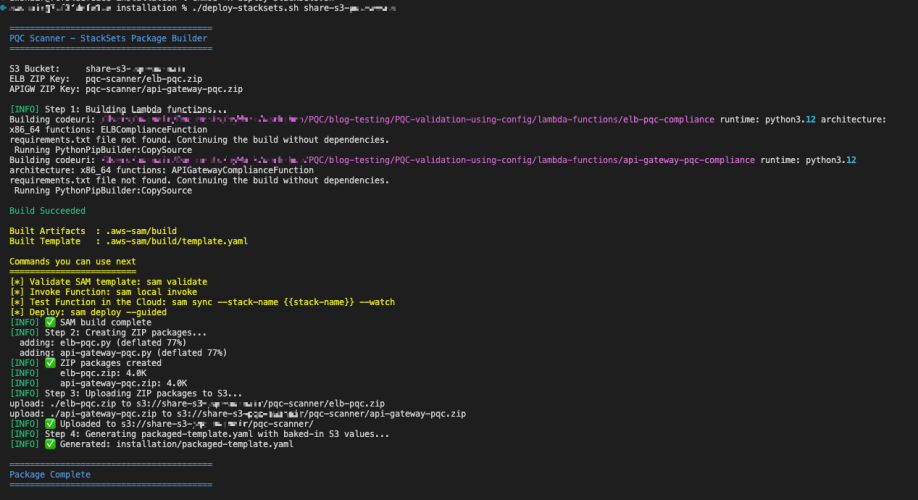
This script automatically:

  • Builds Lambda functions using SAM
  • Creates ZIP packages
  • Uploads ZIPs to the shared S3 bucket
  • Generates packaged-template.yaml with S3 values baked in (no parameters needed at deploy time)
Sample script output of successful upload of the lambda packages to S3 bucket

Figure 4: Sample script output of successful upload of the lambda packages to S3 bucket

Step 2: Deploy Lambda Functions via StackSets

Run the following from the management account (or delegated admin account):

# Create StackSet (--region sets the StackSet "home region" where it is managed)
aws cloudformation create-stack-set \
  --stack-set-name pqc-readiness-lambda-functions \
  --template-body file://packaged-template.yaml \
  --capabilities CAPABILITY_IAM \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=false \
  --region us-east-1

# Deploy stack instances to member accounts
# --regions = target regions where Lambda functions are deployed in member accounts
# --region  = must match the StackSet home region above
aws cloudformation create-stack-instances \
  --stack-set-name pqc-readiness-lambda-functions \
  --deployment-targets OrganizationalUnitIds=ou-xxxx-xxxxxxxx \
  --regions us-east-1 \
  --region us-east-1

Important — StackSet home region vs deployment regions:

  • --region (on each CLI command) = the StackSet home region where the StackSet resource lives. Subsequent operations (describe, update, delete) must specify this same region.
  • --regions (on create-stack-instances) = the deployment target region(s) where stack instances are created in member accounts.
  • These are independent values. Specify --region explicitly to avoid accidental deployment to your CLI’s default region.

Note: SERVICE_MANAGED StackSets must be created from the management or delegated admin account. The management account itself is excluded from stack instance deployments — use deploy-per-regions.sh separately if you need the scanner in the management account.

Step 3: Deploy Organization Conformance Pack

aws configservice put-organization-conformance-pack \
  --organization-conformance-pack-name pqc-legacy-tls-compliance \
  --template-body file://conformance-packs/pqc-legacy-tls-conformance-pack.yaml

This creates Config rules in each member account that reference their local Lambda functions.

    Migration guidance and prioritization

    The three-tier system provides PQC migration priorities:

    High priority – Tier 3 (not PQ-ready):

    • Target: Resources without PQC support. This includes endpoints not using PQ-ready security policies, endpoints that still allow TLS 1.0 or 1.1.
    • Action: Upgrade to a PQ-ready policy containing PQ in its name, such as those ending with -PQ-2025-09 (see Elastic Load Balancing security policies documentation for the full list).
    • Important: Before upgrading to a PQ-ready policy, audit your client TLS versions. PQ-ready policies require TLS 1.3 support; legacy clients that only support TLS 1.2 or earlier will fail to negotiate a connection. Start with a Tier 2 backward-compatible policy (which supports both TLS 1.2 and 1.3 with PQC), monitor connection logs for TLS negotiation failures, and only move to a Tier 1 TLS 1.3-only policy after confirming that your clients support TLS 1.3 with PQC key exchange.
    • Risk: Endpoints don’t support post-quantum cryptography for data in transit. Legacy TLS protocols are vulnerable to current cryptographic attacks.

    Low priority – Tier 2 (PQ-ready, backward compatible):

    • Target: Resources using TLS 1.3 + PQ-ready policies that also support TLS 1.2 for backward compatibility.
    • Action: Consider TLS 1.3-only policies when client compatibility analysis confirms connecting clients support TLS 1.3.
    • Risk: Minimal. These resources already support PQ-TLS with TLS 1.3 connections. TLS 1.2 and earlier fallback maintains backward compatibility, which might indicate some clients aren’t negotiating in PQ-TLS. Remediation is to monitor logs, identify the volume of these connections and clients and plan migration for these clients to use TLS 1.3 with PQ-TLS.

    No action – Tier 1 (PQ-ready, optimal):

    • Target: Resources using TLS 1.3 only with PQC key exchange: These resources meet the target state. No migration needed.

    Viewing the results

    In each member account, navigate to AWS Config Console in the deployed region.

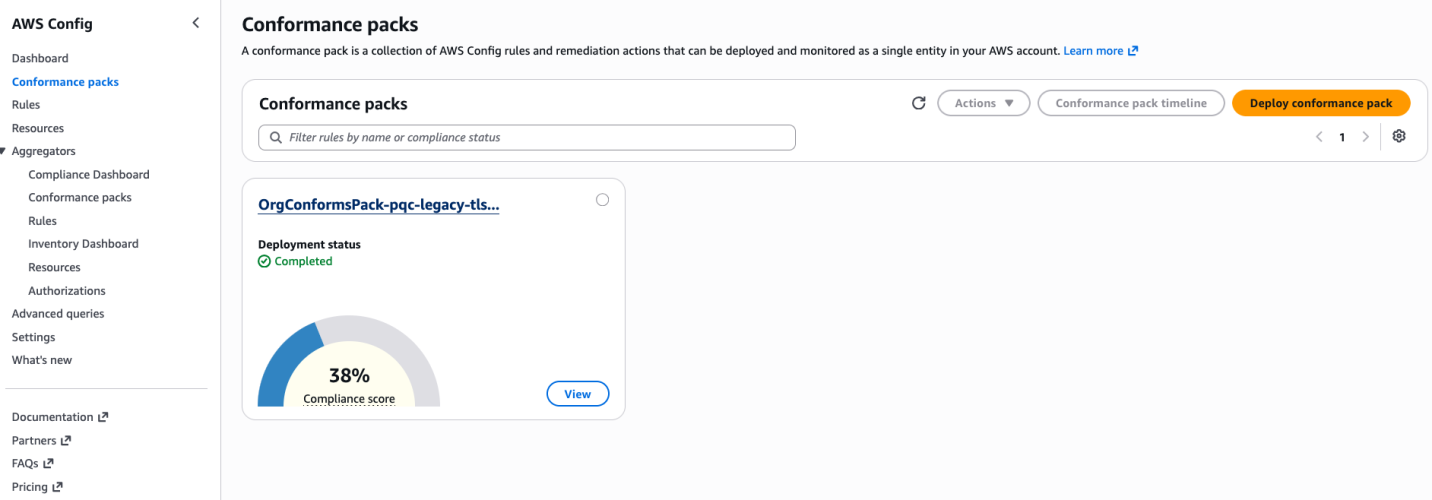
    Conformance Pack View

    Go to AWS Config → Conformance packs and look for:

    OrgConformsPack-pqc-legacy-tls-compliance-

    Note: Organization conformance packs are prefixed with OrgConformsPack- and have a random suffix appended (e.g., OrgConformsPack-pqc-legacy-tls-compliance-gyv22je0).

    PQC Conformance Pack Compliance Score is the percentage of the number of compliant rule-resource

    Figure 5: PQC Conformance Pack Compliance Score is the percentage of the number of compliant rule-resource

    Click the conformance pack to see an overall compliance summary across all 4 rules.

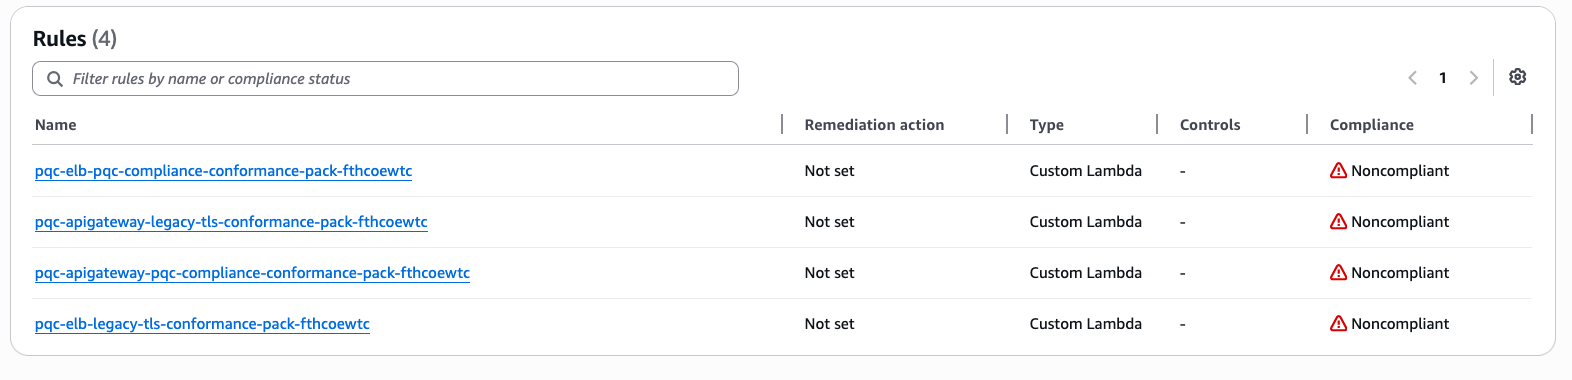
    Individual Rules View

    Go to AWS Config → Rules and find 4 rules with prefix pqc-:

    • pqc-elb-pqc-compliance-conformance-pack-
    • pqc-elb-legacy-tls-conformance-pack-
    • pqc-apigateway-pqc-compliance-conformance-pack-
    • pqc-apigateway-legacy-tls-conformance-pack-

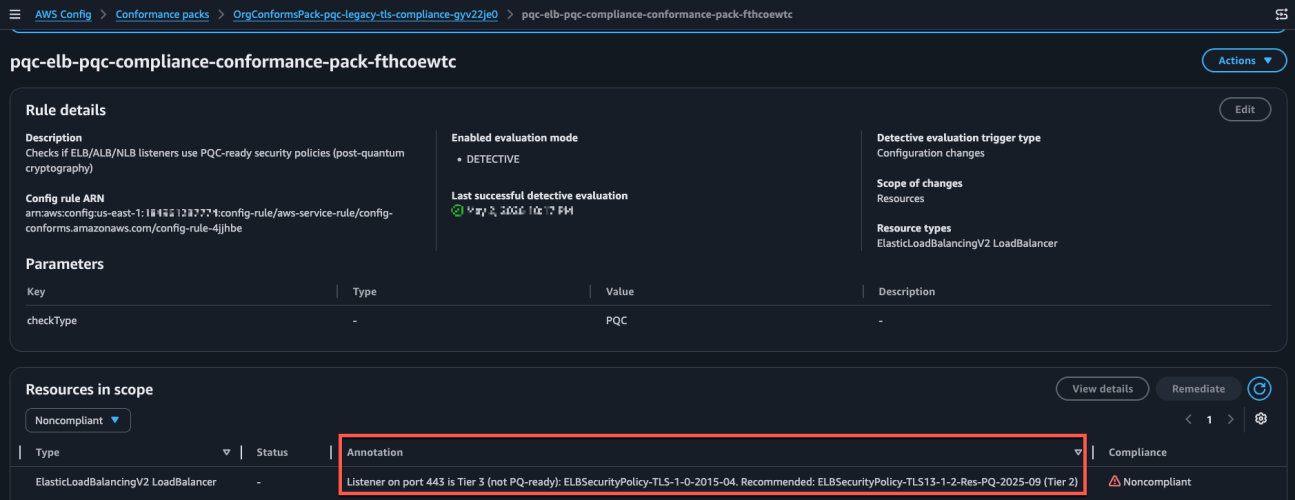
    Click any rule to view:

    • Compliant vs non-compliant resource counts
    • Detailed annotations for each resource
    • Resource ARNs and current security policy configurations
    Visibility into Config rules status inside the conformance pack

    Figure 6: Visibility into Config rules status inside the conformance pack

    Sample image of the config rule findings and annotation describing the migeration guidance based on 3-tier classification.

    Figure 7: Sample image of the config rule findings and annotation describing the migration guidance based on 3-tier classification.

    Conclusion

    After deploying the PQC Readiness Scanner, you gain visibility into TLS posture across AWS edge services, which reduces manual configuration reviews. The tier system provides specific upgrade recommendations so teams can understand next steps without cryptographic expertise. The scanner automatically detects configuration changes to help new deployments maintain readiness standards. Built-in AWS Config reporting supports audit requirements and demonstrates measurable progress toward PQC readiness.

    Deploy the PQC Readiness Scanner and review your results with PQC Readiness Scanner. Start migration with high priority Tier 3 resources and monitor progress across your accounts using AWS Config aggregators.

    Additional resources

    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS Config re:Post or contact AWS Support.

    Pravin Nair

    Pravin Nair

    Pravin is a Senior Security Solutions Architect specializing in data protection and privacy at AWS. He partners with customers to architect secure, scalable cloud solutions that address complex security challenges across encryption, infrastructure protection, and privacy engineering. His expertise spans encryption at rest and in transit, infrastructure security, privacy-based architectures, and emerging security domains including generative AI security and post-quantum cryptography.

    Securing client confidentiality at scale: Automated data discovery and governed analytics for legal workloads

    Post Syndicated from Rohan Kamat original https://aws.amazon.com/blogs/big-data/securing-client-confidentiality-at-scale-automated-data-discovery-and-governed-analytics-for-legal-workloads/

    Automating data security and analytics for legal documents presents a unique challenge when your legal team stores documents with strong access controls, organized by client and matter, encrypted at rest, and governed by well-defined policies. But what happens when you want to run analytics across those repositories? The typical path is extracting content into separate data pipelines or third-party tools, which fragments your governance model and introduces new risks. Law firms and corporate legal departments operate under distinct obligations that make data governance non-negotiable. Attorney-client privilege, work product doctrine, and professional conduct rules impose strict duties around how client information is handled, accessed, and disclosed. Governance failure in this context isn’t just a compliance gap, it can result in privilege waiver, disqualification from representation, or disciplinary action.

    Legal professionals use ethical walls, also called information barriers, as structural safeguards that prevent the flow of confidential information between teams within a firm that represent adverse or potentially conflicting interests. Professional conduct rules mandate these barriers, and failure to maintain them can result in firm disqualification, malpractice liability, or regulatory sanctions.

    Privilege boundaries are equally critical. Attorney-client privilege and work product protection apply only when you properly control access to the underlying material. If you expose privileged documents or metadata about their contents to unauthorized individuals, you risk losing your privilege protection. When organizations fail to maintain reasonable controls over privileged material, courts might find that they have waived their privilege. You should therefore actively manage your access governance, not only as a security concern but as a legal preservation requirement.When you extract content into separate analytics systems or grant broader access than your matter structures support, you create pressure on both protections. You gain visibility but lose confidence in your controls.

    In this post, we show you a reference architecture that automates sensitive data discovery across legal document repositories on Amazon Web Services (AWS), demonstrate how to capture structured findings as a compliance dataset, and guide you through building a governed analytics workspace that maintains your security boundaries. You walk away with a practical model for building security and analytics into the same lifecycle, without moving documents outside their system of record.

    Analytics shouldn’t weaken governance

    Most legal organizations have invested heavily in securing their document repositories. You store documents in structured storage, organized by client and matter. You access controls map to matter boundaries (the organizational and access structures that separate one client engagement from another). You establish retention and hold policies.The difficulty starts when teams want to analyze what’s inside those repositories. Running analytics typically means copying content into a separate system, standing up a new data pipeline, or granting broader access than existing matter structures support. Each of these steps introduces governance gaps. Manual reporting fills some of the void, but it doesn’t scale and can’t provide continuous visibility. What’s missing is a model where security controls and analytics reinforce each other, where the act of discovering sensitive data also produces the dataset that you use for reporting, and where governance applies once and carries through every downstream operation.

    Automation addresses this by combining continuous sensitive data discovery with governed analytics, built on discovery metadata rather than document copies. This automated approach delivers four key advantages:

    • No document movement. Your files stay in their system of record. Analytics runs against structured discovery metadata, not document content, so governance boundaries remain intact.
    • Continuous discovery instead of manual scanning. Automated classification identifies regulated and sensitive information on an ongoing basis, replacing periodic manual reviews with on demand visibility.
    • Unified governance. You define matter-aligned access policies once, and they carry through from document storage to findings analytics and compliance reporting.
    • Built-in audit readiness. A durable record of discovery findings and remediation actions accumulates automatically over time, giving you structured evidence for client reviews and regulatory inquiries.

    Reference Architecture

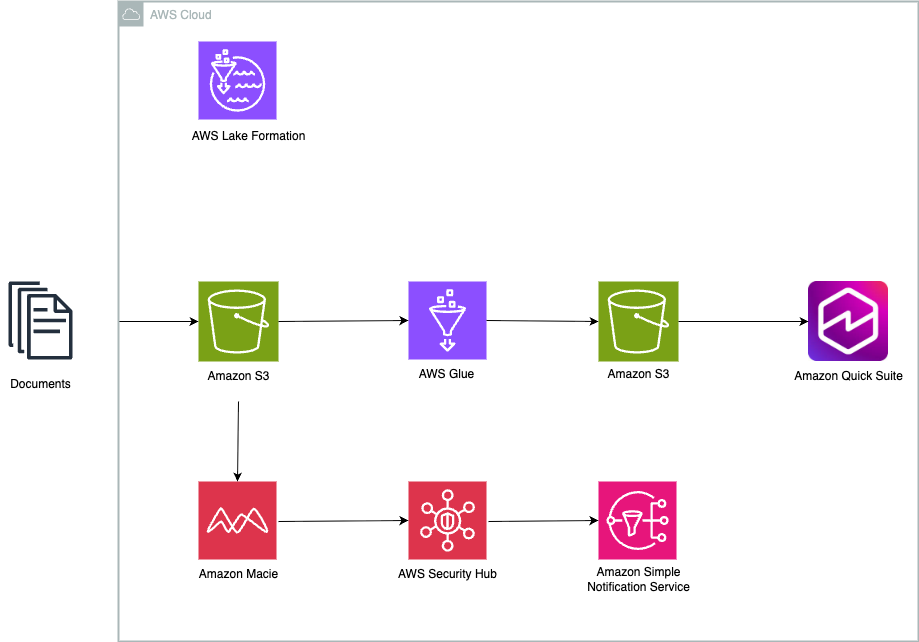
    The following architecture shows how continuous discovery, governance, and compliance operations can work together without copying legal documents into analytics systems.

    This reference architecture illustrates how law firms and corporate legal departments can automate sensitive data discovery and compliance analytics on AWS without moving documents outside their system of record

    Architecture walkthrough

    Store and protect documents in Amazon Simple Storage Service (Amazon S3)

    Store your legal documents in Amazon S3, which serves as the system of record for document content. Align your buckets and prefixes to client and matter structures so that access controls map directly to matter boundaries. Where your retention or legal hold requirements demand it, apply S3 Object Lock to enforce immutability. You can encrypt your data using AWS Key Management Service (AWS KMS), which gives you centralized control over encryption keys and policies.

    Discover and classify sensitive data with Amazon Macie

    You will configure Amazon Macie to continuously analyze your document repositories. Macie identifies regulated information such as personally identifiable information (PII), financial data, and other sensitive content and produces structured findings that describe what Macie identified and where it exists. This provides ongoing visibility into data exposure without requiring document movement or manual scanning.

    Catalog and govern findings with AWS Glue and AWS Lake Formation

    You will use AWS Glue to catalog the findings dataset and maintain its schema so it stays query-ready. Apply AWS Lake Formation tag-based policies to govern access, aligning tags to client, matter, and confidentiality tier. This approach enforces ethical walls and least-privilege access consistently across analytics and reporting activities.

    AI-powered chat agent using Amazon Quick Suite

    You can create custom chat agents to tailor conversational interfaces for specific legal business needs. These agents can be configured with legal-specific knowledge bases, connected to relevant document repositories, and customized with instructions appropriate for legal workflows. You can use this chat agent to interact with your legal documents through natural language conversation for capabilities like:

    • E-Discovery:Search and analyze large volumes of legal documents to quickly find relevant information across your document repository.
    • Contract Analysis:Review contracts and automatically extract key terms, clauses, and obligations to streamline your contract review process.

    The chat agent can help you navigate complex document sets through conversational queries, making legal research and document review more efficient and accessible.

    Analyze and report with Amazon Quick Sight

    You will use Amazon Quick as your compliance operations workspace. Quick provides a unified environment where your teams can query findings, generate dashboards, track remediation actions, and produce audit-ready reports. The agentic AI capabilities of Amazon Quick can autonomously build analyses, surface anomalies across matters, generate executive summaries for client reviews, and proactively recommend remediation priorities based on finding severity and trends. Combined with built-in data stories for automated narrative generation and pixel-perfect paginated reports for regulatory submissions, Quick reduces the time from discovery to action while keeping your teams within a governed interface aligned to matter-based permissions. Rather than switching between separate visualization, workflow, and reporting tools, your legal and compliance teams can review findings, manage response activities, and collaborate all within a single workspace that respects ethical walls and privilege boundaries.

    Escalate high-severity findings

    For high-severity findings that demand immediate attention, route alerts through AWS Security Hub or Amazon Simple Notification Service (Amazon SNS) to trigger escalation workflows. This connects visibility directly to action when your teams identify sensitive data risks.

    Why this approach works for legal

    Documents stay where they belong. Your files remain in Amazon S3, aligned to client and matter boundaries. No content moves into separate analytics pipelines.Ethical walls remain intact. Because analytics is built on discovery findings and not document copies, you can govern access to findings using the same matter-aligned controls that apply to documents. Compliance and security teams gain visibility without expanding document access.Discovery runs continuously, not periodically. Rather than scheduling quarterly or annual scans, you maintain a current view of sensitive data across your repositories.

    Governance applies once and carries through. Lake Formation tag-based policies govern findings access at the catalog level. You define your matter and confidentiality mappings once, and they carry through to every dashboard, query, and report.Audit readiness is built in. Instead of assembling reports manually before a client review or regulatory inquiry, you maintain a historical record of discovery findings and remediation actions. You can demonstrate your posture over time with consistent, structured evidence.

    Security and analytics reinforce each other. Your analytics capability is built on top of your security controls, not alongside them. Strengthening one strengthens the other.

    Cost considerations

    The primary cost drivers for this architecture include:

    • Amazon Macie: You pay based on the number of S3 buckets evaluated and the volume of data inspected for sensitive data discovery. Review Amazon Macie pricing for current rates.
    • Amazon S3: Storage costs for both your document repositories and the compliance intelligence bucket. Consider S3 lifecycle policies to tier older findings into lower-cost storage classes.
    • AWS Glue and AWS Lake Formation: Charges for crawlers and catalog storage. For most implementations, these costs are modest.
    • Amazon QuickSight: Per-user pricing based on the edition that you select (Standard or Enterprise). Enterprise edition supports row-level and column-level security, which aligns well with matter-based governance.
    • Amazon EventBridge, AWS Security Hub, and Amazon SNS: Charges based on event volume and notifications delivered. For findings-based workflows, these costs are generally low.

    Use the AWS Pricing Calculator to estimate costs based on your repository size, user count, and discovery frequency.

    Getting started

    Start by identifying a representative set of document repositories in Amazon S3. We recommend that you start with two or three matters that span different practice areas and confidentiality tiers.

    1. Turn on Amazon Macie for those repositories and configure automated sensitive data discovery.
    2. Catalog the findings dataset with AWS Glue and apply Lake Formation tag-based access policies aligned to your matter structure.
    3. Build your first Amazon Quick Sight dashboard to visualize findings by matter, sensitivity type, and severity.
    4. Define escalation rules in AWS Security Hub or Amazon SNS for high-severity findings.

    After you validate this workflow against your initial repositories, expand gradually. Add more repositories to Macie discovery. Refine your governance tags to reflect practice areas and confidentiality tiers. Extend your dashboards from basic posture visibility to trend analysis and remediation tracking.The goal isn’t to build a comprehensive analytics solution all at once. Start with a secure foundation where discovery findings, governance, and reporting operate together in a way that aligns with your legal workflows, and then expand from there.

    Conclusion

    You don’t have to choose between protecting client data and understanding it. By building analytics on top of governed discovery findings and using a unified compliance workspace, you gain visibility into your data posture without weakening confidentiality boundaries.This approach brings security, governance, and analytics together in a way that reflects how legal work is actually structured. It provides continuous visibility, supports audit readiness, and delivers insight without requiring documents to move outside their system of record.

    Next steps

    Review the Amazon Macie User Guide to understand sensitive data discovery configuration options and Amazon Quick Sight documentation to evaluate dashboard and row-level security capabilities.

    Contact your AWS account team to discuss implementation support for legal and compliance workloads.


    About the authors

    Photo of Author - Rohan Kamat

    Rohan Kamat

    Rohan Kamat is a Solutions Architecture Leader within HCLS with extensive experience in cloud architecture, cybersecurity, Identity and Access Management, and enterprise networking. Rohan focuses on helping architects build both depth in cloud technologies and strength in executive communication, making sure they can confidently guide organizations through business and technical transformation. Outside of his professional work, Rohan enjoys time with his family, organizing community cricket events, and exploring fitness and wellness activities like pickleball and ping pong. He also enjoys planning travel experiences that bring people together and create lasting shared memories.

    Photo of Author- Miguel Lopez Luis

    Miguel Lopez Luis

    Miguel Lopez Luis is an AWS Solutions Architect who works with small and medium businesses across the United States. He graduated with a Bachelor’s degree in Cybersecurity from Bellevue University in Nebraska and is a member of the Omega Nu Lambda Honor Society. Leveraging his extensive expertise in business management, Miguel is passionate about planning strategic initiatives, leading cross-functional teams, and mentoring others. In his personal time, he enjoys activities that involve travel, sports, and cooking.

    Photo of Author - Pranali Khose

    Pranali Khose

    Pranali Khose is an AWS Solutions Architect based in Seattle. She works directly with small and medium business (SMB) customers across the United States, to design and implement cloud solutions that address their unique business challenges and accelerate digital transformation. Pranali holds a Master of Science in Computer Science from the University of Texas at Arlington.

    Agentic application modernization at scale with Strands and Amazon Transform custom

    Post Syndicated from Kanishk Mahajan original https://aws.amazon.com/blogs/devops/use-generative-ai-agents-for-application-modernization-at-scale-with-strands-amazon-transform-custom-and-amazon-bedrock-agentcore/

    Introduction

    Modernizing applications by upgrading language runtimes, migrating SDKs, and refactoring frameworks is important for cloud adoption but can be labor-intensive at scale. Each repository requires analysis of dependencies and transformation needs; custom transformation logic must be built and validated, and changes are often executed sequentially across codebases. If you have hundreds of applications, this stretches timelines from months to years, while introducing inconsistency across your teams.

    To address this, Amazon Web Services (AWS) provides a composable set of building blocks. AWS Transform custom enables reusable, CLI-driven code transformations for upgrading runtimes, SDKs, and frameworks consistently across large portfolios. Strands Agents provides a framework for building multi-agent systems that coordinate complex transformation workflows. Amazon Bedrock AgentCore delivers the managed runtime, memory, and observability to operate these agents reliably in production. Together, they replace manual, sequential modernization with an intelligent, automated approach that scales.

    In this post, we show you how to combine these services to build a generative AI–powered, agentic modernization system that can automatically analyze application repositories, determine required changes, create missing transformations, and execute them in parallel at scale.

    Solution overview

    The solution uses an agentic architecture that separates intelligent decision-making from deterministic execution, enabling automation at scale while maintaining consistency and control. In this post, you will build an AI-driven application modernization system that demonstrates how multi-agent workflows can be applied to large-scale code transformation scenarios. You interact with the system through a React-based frontend or API interface, submitting individual repositories or batch workloads via CSV inputs. Requests are processed asynchronously through an API layer that invokes an orchestrator agent running on Amazon Bedrock AgentCore, which coordinates specialized agents to analyze codebases, identify transformation requirements, and manage execution workflows. Results are stored and surfaced through the interface, allowing users to track progress and review outputs in real time.The workflow begins with repository analysis, where the system inspects application codebases to identify languages, dependencies, and required upgrades such as runtime version changes or SDK migrations. Based on this analysis, the system maps each application to an existing transformation when available. If no suitable transformation exists, a creation agent dynamically generates one using natural language instructions and publishes it to a centralized registry for reuse, creating a continuously improving system where transformation coverage expands over time.

    Once transformations are identified or created, an execution agent runs them at scale by invoking AWS Batch jobs that execute the AWS Transform custom CLI, enabling parallel processing across multiple repositories. The orchestrator coordinates all agents, maintains workflow state using Amazon Bedrock AgentCore Memory, and ensures reliable execution through structured task decomposition, tool invocation, and error handling. While the example focuses on application re-platforming, the same architectural pattern can be applied to other large-scale code analysis and automation workflows.

    The following architecture diagram (Figure 1) illustrates the various components of our solution as outlined in this section:architecture diagram describing the multi agent strands and agentcore deployment

    Figure 1: AWS Transform custom Agentic Orchestration Architecture using Strands agents and Amazon Bedrock AgentCore

    Prerequisites

    Complete the following prerequisites:

    1. Install the AWS Command Line Interface (AWS CLI).
    2. Install the AWS SAM CLI v1.100.0+
    3. Install Docker v20.x+.
    4. Install Node.js v18.x+
    5. Install Python v3.11+
    6. Install the AWS CDK CLI
    7. Enable access to a Bedrock model for the orchestrator in your deployment region. The default model can be configured through the Amazon Bedrock model access console. To use a different model, set `BEDROCK_MODEL_ID` in `deployment/config.env` before Step 3 and enable access to that model instead. Model access approval can take a few minutes in some accounts, so complete this step before deploying.

    Dependencies

    The Strands Agents implementation has the following dependencies that are packaged in the DockerFile:

    1. Strands multi-agent framework: strands-agents
    2. Strands agent tools and utilities: strands-agents-tools
    3. HTTP library for API calls: requests
    4. Amazon Bedrock AgentCore SDK: bedrock-agentcore
    5. AWS SDK for Python: boto3

    Deploy the solution

    The solution is available for download on the GitHub repo. This post walks through the CDK + SAM deployment path (Option A in the repository README). The repository also includes a CDK-only option (Option B); see the repository README for details.

    Step 1: Clone the repository

    git clone https://github.com/aws-samples/aws-transform-custom-samples.git

    cd aws-transform-custom-samples/agentic-atx-platform

    Step 2: Configure AWS Credentials

    # Configure AWS CLI

    aws configure

    # Verify credentials

    aws sts get-caller-identity

    Step 3: Deploy ATX CLI Container image and frontend using AWS CDK

    # Copy configuration template (defaults work for most setups; edit only to change region or Bedrock model)

    cd deployment

    cp config.env.template config.env

    # Authenticate with Amazon ECR Public (required for the Docker base image pull)

    aws ecr-public get-login-password --region us-east-1 | docker login --username AWS --password-stdin public.ecr.aws

    # Build the UI placeholder so CDK’s UI stack has ui/dist/ to deploy

    cd ../ui && npm install && npx vite build

    # Install CDK dependencies and bootstrap (run once per account/region)

    cd ../cdk

    npm install cdk bootstrap

    # Build TypeScript and deploy the three stacks

    npx tsc

    CDK_DEFAULT_ACCOUNT=$(aws sts get-caller-identity --query Account --output text)

    cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never

    # Note for accounts without a default VPC , pass the VPC context flags to `cdk deploy`:

    cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never

    cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never -c existingVpcId=vpc-xxx -c existingSubnetIds=subnet-aaa,subnet-bbb -c existingSecurityGroupId=sg-ccc

    # Subnets must be public (auto-assign public IP enabled) or private with a NAT gateway so Fargate tasks can reach Amazon ECR, Amazon S3, and Git repositories.

    Step 4: Deploy Strands Agents to AgentCore runtime using AWS SAM

    cd ../sam./deploy.sh

    # Invoke the deploy Lambda to create the AgentCore Runtime via the bedrock-agentcore-control SDK (takes 2-5 minutes)

    aws lambda invoke --function-name atx-deploy-agentcore \ --region us-east-1 \ --cli-binary-format raw-in-base64-out \ --payload '{"action":"deploy"}' \ --cli-read-timeout 900 /tmp/deploy-output.jsoncat /tmp/deploy-output.json

    Step 5: Wire the AgentCore runtime ARN into the async invoke Lambda

    ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)

    RUNTIME_ARN=$(python3 -c "import json; print(json.loads(json.load(open('/tmp/deploy-output.json'))['body'])['runtime_arn'])")aws lambda update-function-configuration \ --function-name atx-async-invoke-agent \ --region us-east-1 \ --environment "Variables={AGENT_RUNTIME_ARN=${RUNTIME_ARN},RESULT_BUCKET=atx-custom-output-${ACCOUNT_ID},JOBS_TABLE=atx-transform-jobs}"

    Step 6: Rebuild and deploy the frontend with AgentCore API endpoint

    # Update the React application with the deployed API endpoint and redeploy it.

    API_URL=$(aws cloudformation describe-stacks \ --stack-name AtxAgentCoreSAM \ --region us-east-1 \ --query 'Stacks[0].Outputs[?OutputKey==`ApiEndpoint`].OutputValue' \ --output text)

    cd ../ui

    VITE_API_ENDPOINT=$API_URL npx vite build./deploy-aws.sh

    # This rebuilds the React application with the correct API endpoint, uploads it to Amazon S3, and invalidates the Amazon CloudFront distribution.

    Step 7: Access the application

    # After deployment completes, retrieve the CloudFront distribution URL from the AWS CloudFormation outputs and open it in your browser to access the application UI.

    aws cloudformation describe-stacks \ --stack-name AtxUiStack \ --region us-east-1 \ --query 'Stacks[0].Outputs[?OutputKey==`WebsiteUrl`].OutputValue' \ --output text

    Using the application

    The UI exposes five tabs covering the complete modernization workflow: browsing available transformations, executing a transformation on a single repository, creating a new custom transformation with natural language, batch-processing a CSV of repositories, and tracking job status. This section walks through two of the most common flows.

    Create a custom transformation from natural language

    Open the Create Custom tab, describe the transformation in plain English (for example, “Upgrade Spring Boot 2 applications to Spring Boot 3”), and optionally provide a reference repository URL. The creation agent analyzes the source, generates a transformation definition, and publishes it to the ATX registry for reuse across the portfolio.

    Describing a custom transformation in plain English. The form accepts a name, description, optional reference repository, and natural-language requirements.

    Figure 2: Describing a custom transformation in plain English. The form accepts a name, description, optional reference repository, and natural-language requirements.After submitting, the orchestrator clones the reference repository, analyzes the source, and generates a transformation definition tailored to the actual code patterns found in the codebase. This takes 1–5 minutes depending on repository size. The generated definition is then shown for review in the Jobs tab, where it can be edited before publishing to the ATX registry.

    Figure 3: The AI-generated transformation definition shown for review in the Jobs tab. The agent analyzed the Flask codebase and produced a detailed definition covering routes, request handling, response patterns, and Blueprint architecture. The user can edit the definition in-place and click Publish to Registry when ready.Once published, the new transformation appears in the Transformations tab alongside AWS-managed transformations and can be executed the same way on any repository.

    Run a batch of repositories from a CSV

    Open the CSV Batch tab and upload a CSV listing repository URLs and target transformations. A sample `sample-batch.csv` is included in the repository at `agentic-atx-platform/ui/sample-batch.csv`. The preview shows the parsed rows before submission. On Submit All, each row becomes a separate AWS Batch job running in parallel, and the Jobs tab shows live status as repositories complete.

    Uploading a batch of repositories for parallel processing. The CSV lists a source repository URL, target transformation, optional validation commands, and additional plan context per row.

    Figure 4: Uploading a batch of repositories for parallel processing. The CSV lists a source repository URL, target transformation, optional validation commands, and additional plan context per row. Each row becomes an independent AWS Batch job on submission.

    Clean up

    To avoid recurring charges, remove the resources after trying the solution.

    Step 1: Delete the SAM Stack

    sam delete --stack-name AtxAgentCoreSAM --region us-east-1 --no-prompts

    Step 2: Delete the CDK Stacks

    Remove the three CDK stacks in reverse order. The S3 buckets are configured with `autoDeleteObjects: true`, so CDK will empty them before deletion.

    cd cdk

    npx cdk destroy AtxUiStack AtxInfrastructureStack AtxContainerStack --force

    Conclusion

    In this post, you learned how to build a generative AI–powered, agentic system for application modernization that can analyze application repositories, determine required code changes, create missing transformations, and execute those transformations at scale. By combining AWS Transform Custom for transformation execution with Amazon Bedrock AgentCore for orchestration, and Strands Agents for multi-agent coordination and AWS Transform container solution for parallel processing, this approach demonstrates how intelligent automation can be applied to large-scale code transformation workflows.

    This solution directly addresses the challenges of traditional modernization approaches. It reduces manual effort by automating repository analysis and transformation mapping, eliminates gaps in transformation coverage by dynamically generating reusable transformations, and significantly improves scalability through parallel execution using AWS Batch.

    By introducing a centralized, agent-driven workflow with built-in observability and state management, organizations can achieve faster, more consistent, and governed modernization across large application portfolios. To get started, deploy the solution in your AWS environment, test it with a sample repository or batch workload, and extend it by creating custom transformations tailored to your applications. You can further integrate this approach into your CI/CD pipelines to enable continuous modernization and accelerate your cloud migration initiatives.


    About the authors

    Kanishk Mahajan is Principal – AI/ML with AWS Professional Services. In this role, he leads GenAI and agentic transformations for some of AWS largest customers in Telco and Media & Entertaintment.

    Sandeep Batchu is a Senior Security Architect at Amazon Web Services, with extensive experience in software engineering, solutions architecture, and cybersecurity. Passionate about bridging business outcomes with technological innovation, Sandeep guides customers through their cloud and generative AI journey, helping them design and implement secure, scalable, and resilient architectures in the era of AI-driven transformation.
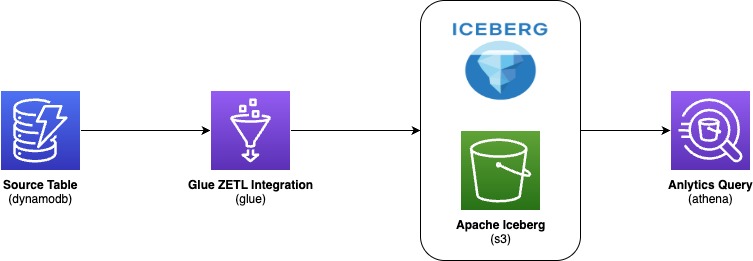
    Venugopalan Vasudeven (Venu) is a Principal Specialist Solutions Architect at AWS, where he leads Agentic AI initiatives focused on AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

    Improve DynamoDB analytics with AWS Glue zero-ETL schema and partition controls

    Post Syndicated from Raju Ansari original https://aws.amazon.com/blogs/big-data/improve-dynamodb-analytics-with-aws-glue-zero-etl-schema-and-partition-controls/

    You store transactional data in Amazon DynamoDB and get single-digit millisecond performance. However, when you want to run analytics, machine learning (ML), or reporting on that same data, you face a gap: your flexible, semi-structured DynamoDB schemas don’t align with the flat, columnar formats that analytics engines require. Bridging this gap typically means building and maintaining custom ETL pipelines, which adds development cost and operational overhead.

    AWS Glue Zero-ETL integration removes that pipeline work. It enables replication of your DynamoDB tables to Apache Iceberg tables in Amazon Simple Storage Service (Amazon S3), then query it directly with Amazon Athena. During setup, you can configure two capabilities that will shape how replicated data looks and performs: schema unnesting flattens nested attributes into individual columns, and data partitioning organizes data so your queries scan only what they need.

    In this post, you learn how to replicate Amazon DynamoDB data to Apache Iceberg tables in Amazon S3 through a zero-ETL integration. We walk through the challenges that the DynamoDB nested, schema-flexible data model introduces for analytics workloads, and show you how to configure schema unnesting and data partitioning for a sample product catalog table. We also cover how to query the replicated data in Amazon Athena using standard SQL.

    Semi-structured data meets analytics

    Your product catalog in DynamoDB contains items with nested attributes like product details, pricing tiers, and inventory information. A typical item looks like this:

    {
      "product_id": "P-1001",
      "name": "Wireless Headphones",
      "productdetails": {
        "brand": "AudioTech",
        "category": "Electronics",
        "weight_kg": 0.25,
        "specification": {
           "color": "Black",
           "storage": "128GB"
        }
      },
      "pricing": {
        "list_price": 79.99,
        "discount_pct": 10
      },
      "created_at": 1701388800000
    }

    This structure supports fast transactional reads and writes. However, when you replicate this data for analytics, you face two decisions:

    • You must decide whether to flatten nested maps like productdetails into individual columns or preserve them as-is.
    • You must choose how to organize the data on disk so that queries filtering by brand or date range scan only relevant partitions.

    With AWS Glue Zero-ETL, you address both decisions through configurable schema unnesting and data partitioning.

    Solution overview

    You replicate data from your DynamoDB table through AWS Glue Zero-ETL into Apache Iceberg tables stored in Amazon S3, then query the results with Amazon Athena. The following diagram illustrates the end-to-end architecture:

    Data flow diagram showing AWS data pipeline: DynamoDB source table → AWS Glue zero-ETL integration → Apache Iceberg on Amazon S3 → Amazon Athena analytics query.

    AWS Glue zero-ETL ingests data from Amazon DynamoDB, writes it in Apache Iceberg format to your Amazon S3 data lake, and makes it available for SQL queries in Amazon Athena—with no pipelines to build or maintain. With this integration, you:

    • Save development time by skipping custom code and ETL job management
    • Keep DynamoDB performance intact because replication doesn’t consume table’s provisioned read/write capacity
    • Get data within 15 minutes of changes in the source table
    • Query with standard tools because data lands in Apache Iceberg format, an open table format that AWS natively supports for high-performance analytics

    During setup, you configure two output settings:

    1. Schema unnesting in Zero-ETL: You choose how nested attributes appear in the target. Flattening nested maps into individual columns streamlines your queries and reduces complexity.
    2. Data partitioning in Zero-ETL: You choose how data is organized into partitions. When you filter on a partition column, the query engine reads only matching data instead of scanning everything, cutting both query time and cost.

    Schema unnesting

    When you create a zero-ETL integration, you can choose one of three unnesting options. Schema unnesting transforms complex, nested DynamoDB structures into formats that analytics engines can query directly, removing post-processing transformations.

    Each option changes how nested DynamoDB attributes appear in the target table. The right choice depends on your analytics tools and how consistent your DynamoDB schemas are.

    Option 1: No unnesting

    This option preserves the original nested structure. DynamoDB maps and lists remain as structured columns in the target.

    Using the product example, the target table retains productid and value as columns to hold DynamoDB partition key and a DynamoDB record respectively.

    Recommended for: Workloads where your analytics tools natively support querying nested data and you want to preserve the DynamoDB structure unchanged.

    Option 2: Unnest one level

    This option flattens top-level maps into individual columns. Lists remain nested.

    With this option, productdetails and pricing each become separate columns.

    Recommended for: Scenarios where your DynamoDB items have a consistent schema and you want to balance structure preservation with query simplicity.

    Option 3: Unnest all levels (default)

    This option recursively flattens nested structures using dot notation and produces the flattest schema.

    For the product table, this creates columns such as productdetails.brand, productdetails.category, productdetails.specification.color , productdetails.specification.storage , pricing.list_price, and pricing.discount_pct. The pricing map flattens similarly. Each column is directly queryable without nested access patterns.

    Recommended for: Analytics tools that prefer flat schemas when your DynamoDB items have a reasonably consistent structure. Note that deeply nested or highly variable schemas can produce very wide tables.

    Data partitioning

    You can speed up your queries and reduce costs by partitioning your replicated data. Partitioning divides data into logical segments on disk.

    When you include a filter on a partition column in your query, the query engine skips irrelevant segments entirely. This behavior is called partition pruning: instead of scanning the entire dataset, the engine reads only the data that matches your filter conditions. For large tables, partition pruning can reduce both query runtime and cost significantly.

    Default partitioning

    If you don’t specify partition columns, AWS Glue Zero-ETL partitions data using the DynamoDB primary key with bucketing. This approach supports general-purpose queries without requiring manual configuration. For specific query patterns or performance requirements, you can define custom partitioning strategies described in the subsections that follow.

    Identity partitioning

    Identity partitioning uses raw column values to create partitions. You apply this strategy to low-to-medium cardinality columns such as brand, category, or AWS Region. To partition the product table by productdetails.brand and create a separate partition for each brand, use this configuration:

    {
      "partitionSpec": [
        {
          "fieldName": "productdetails.brand",
          "functionSpec": "identity"
        }
      ]
    }

    With this setup, AWS Glue creates one partition directory per unique brand value. When you query for a specific brand, Athena reads only that partition.

    Important: Avoid identity partitioning on high-cardinality columns such as primary keys or timestamps. This creates many small partitions, which degrades both ingestion and query performance

    Time-based partitioning

    Time-based partitioning organizes data by timestamp at a chosen granularity: year, month, day, or hour. You apply this strategy to time-series data and time-range queries. To partition the product table by month on the created_at column, which stores epoch milliseconds, use this configuration:

    {
      "partitionSpec": [
        {
          "fieldName": "created_at",
          "functionSpec": "month",
          "conversionSpec": "epoch_milli"
        }
      ]
    }

    The conversionSpec parameter tells AWS Glue how to interpret the source timestamp. Supported values: epoch_sec (Unix seconds), epoch_milli (Unix milliseconds), and iso (ISO 8601 format).

    Note: The original column values remain unchanged. AWS Glue transforms only the partition column values to timestamp type in the target table

    Multi-level partitioning

    You can combine strategies for a hierarchical scheme. To partition first by month and then by brand, use this configuration:

    {
      "partitionSpec": [
        {
          "fieldName": "created_at",
          "functionSpec": "month",
          "conversionSpec": "epoch_milli"
        },
        {
          "fieldName": "productdetails.brand",
          "functionSpec": "identity"
        }
      ]
    }
    

    This scheme supports efficient queries that filter by date range, brand, or both. Place higher-selectivity columns first in the hierarchy and align the scheme with your most common query patterns.

    Best practices

    Keep these guidelines in mind when you configure your integration:

    • Avoid identity partitioning on high-cardinality columns such as primary keys, timestamps, or system-generated IDs. This leads to partition explosion and degrades performance.
    • Apply only one time-based function per column. For example, don’t partition col1 by year, month, day, and hour simultaneously.
    • Match conversionSpec to your actual data format. If your timestamps are in epoch milliseconds, use epoch_milli, not epoch_sec or iso.
    • Choose granularity based on data volume. High-volume tables benefit from finer granularity (day or hour). Lower-volume tables work well with coarser granularity (month or year).
    • Account for timezone implications with ISO timestamps. AWS Glue Zero-ETL normalizes timestamp partition values to UTC.

    Prerequisites

    To implement the AWS Glue Zero-ETL integration with a DynamoDB source, you will need:

    1. An AWS account with least privilege principle
    2. An AWS Glue database (for example, ddb_zero_etl_demo_db) with an Amazon S3 bucket associated as the database location (setup instructions)
    3. AWS Glue Data Catalog settings updated with an AWS Identity and Access Management (IAM) policy that grants fine-grained access control for zero-ETL (setup instructions)
    4. Create an IAM role named zetl-role, to be used by zero-ETL to access data from your DynamoDB table
    5. A DynamoDB source table (for example, product) configured for zero-ETL integration (setup instructions)

    Walkthrough: Create the zero-ETL integration

    Complete these steps to create a zero-ETL integration with DynamoDB as the source and Apache Iceberg tables in Amazon S3 as the target.

    Step 1: Select the source type

    1. Open the AWS Glue console.
    2. In the navigation pane, under Data Integration and ETL, choose Zero-ETL integrations.
    3. Choose Create zero-ETL integration.
    4. Select Amazon DynamoDB as the source type, then choose Next.

    AWS Glue console showing Step 1 of creating a Zero-ETL integration — selecting a source type from 14 available data sources including Amazon DynamoDB, Facebook Ads, Instagram Ads, MySQL, Oracle, PostgreSQL, and Microsoft SQL Server

    [Figure 1: Selecting Amazon DynamoDB as the zero-ETL source type]

    Step 2: Configure source and target

    1. In Source details, select your DynamoDB table (for example, product).
    2. In Target details:
      • Select the current account as target.
      • Choose the catalog and target database (for example, ddb_zero_etl_demo_db).
      • Select the IAM role (for example, zetl-role).

    AWS Glue console Step 2 — configuring source and target for a zero-ETL integration with Amazon DynamoDB "product" table as source and an AWS Glue catalog database "ddb_zero_etl_demo_db" as target

    [Figure 2: Configuring source DynamoDB table and target database]

    Step 3: Configure output settings

    1. Under Schema unnesting, select Unnest all fields.
    2. Under Data partitioning, select Specify custom partition keys.
    3. Enter the partition key (for example, productdetails.brand) and set the function to Identity.
    4. Choose Next.

    AWS Glue Zero-ETL integration output settings showing schema unnesting set to "Unnest all fields," custom partition key "productdetails.brand" configured with Identity function, and target table named "product.

    [Figure 3: Configuring schema unnesting and partition key settings]

    Step 4: Set integration details

    1. Optionally configure encryption and replication settings. The default refresh interval is 15 minutes.
    2. Enter a name for the integration (for example, ddb-zero-etl-demo).
    3. Choose Next.

    AWS Glue Zero-ETL integration Step 3 — configuring security with AWS managed KMS key, replication refresh interval set to 15 minutes, and integration named "ddb-zero-etl-demd

    [Figure 4: Configuring encryption and replication settings]

    Step 5: Review and create

    1. Review your settings and choose Create and launch integration.
    2. The integration shows as Active within about a minute.

    AWS Glue Zero-ETL integration Step 4: Review and Create — showing DynamoDB "product" table as source, Glue database "zett_target" as target with IAM role "zett-role," and partition key "productdetails.brand" with Identity function

    [Figure 5: Review and create summary]

    AWS Glue Zero-ETL Integration Details page showing "ddb-zero-etl-demo-test" integration with status "Creating," DynamoDB "product" table as source, Glue database "ddb_zero_etl_demo_db" as target, and a 15-minute refresh interval

    [Figure 6: Integration active with successful status]

    Query the replicated data

    After the integration is active and the initial replication completes (typically 15–30 minutes), you can query the data in Amazon Athena.

    Preview the replicated data

    1. Open the Amazon Athena console.
    2. In the query editor, select your target database (for example, ddb_zero_etl_demo_db).
    3. Run a preview query:
    SELECT * FROM "ddb_zero_etl_demo_db"."product"LIMIT 10;

    Verify schema unnesting

    With Unnest all fields selected, nested attributes appear as individual columns with dot notation:

    SELECT "productdetails.brand", "productdetails.category", "pricing.list_price" 
    FROM "ddb_zero_etl_demo_db"."product"
    WHERE "productdetails.category" = 'Electronics';

    Verify partition pruning

    Queries that filter on the partition column (productdetails.brand) automatically skip irrelevant partitions:

    SELECT product_id, name, "pricing.list_price"
    FROM "ddb_zero_etl_demo_db"."product"
    WHERE "productdetails.brand" = 'AudioTech';

    Amazon Athena Query Editor showing a completed SQL query selecting brand, category, and product ID from a DynamoDB zero-ETL Glue catalog table, returning two results: Samsung SmartPhone P22445 and TechCo SmartPhone P12345

    [Figure 7: Athena query to retrieve the data from Apache Iceberg lakehouse]

    You can verify the partition structure by navigating to the Amazon S3 bucket associated with your database. The data organizes into directories like:

    Amazon S3 bucket browser showing the "data/" folder in "ddb-zero-etl-demo-bucket" with two partitioned folders: "productdetails.brand=Samsung/" and "productdetails.brand=TechCo/" — confirming Iceberg partition structure from DynamoDB zero-ETL integration

    [Figure 8: Amazon S3 bucket organization for the identity partition productdetails.brand]

    Clean up

    To avoid ongoing charges, delete the resources in this order:

    1. Delete the zero-ETL integration. In the AWS Glue console, navigate to Zero-ETL integrations, select your integration, and choose Delete. Existing replicated data remains in the target, but new changes stop replicating.
    2. Delete the replicated table. In the AWS Glue Data Catalog, navigate to Tables, select the replicated table, and delete it.
    3. Delete the AWS Glue database. In the Data Catalog, select the database and delete it.
    4. Delete the Amazon S3 data. Empty and delete the S3 bucket associated with the database.
    5. Delete the DynamoDB table. If you created it for this walkthrough, delete the source table.
    6. Delete IAM resources. Remove the IAM role and policies created for the integration.

    Conclusion

    You configured schema unnesting and data partitioning for a DynamoDB zero-ETL integration, replicated a product catalog table to Apache Iceberg tables in Amazon S3, and verified the results in Amazon Athena. Unnesting flattened nested attributes into directly queryable columns. Partitioning helped the query engine skip irrelevant data, reducing both query time and cost. To take your integration further, try monitoring replication lag and data freshness with Amazon CloudWatch metrics. You can also experiment with different partitioning strategies on a staging table before applying them to production workloads, testing time-based partitioning alongside identity partitioning to find the optimal scheme for your query patterns. For broader analytics coverage, query the same Iceberg tables from Amazon Redshift Spectrum or Amazon EMR alongside Athena. For more details, explore these resources:


    About the authors

    Raju Ansari

    Raju is a Senior Software Development Engineer at AWS, specializing in building scalable, secure, serverless solutions that simplify data analytics and AI agent development. He helps organizations modernize their data analytics infrastructure and develop cutting-edge AI agentic applications. Currently, Raju focuses on building foundational AI services, including Amazon Bedrock Agents, which enable developers to create intelligent, autonomous applications at scale. Outside of work, Raju is passionate about giving back to the tech community. He actively volunteers at IEEE events and mentor early and mid-career professionals

    Shashank Sharma

    Shashank is an Engineering Leader with over 15 years of experience delivering data integration and replication solutions for first-party and third-party databases and SaaS for enterprise customers. He leads engineering for AWS Glue Zero-ETL and Amazon AppFlow, building fully managed pipelines that replicate data from sources like Salesforce, SAP, DynamoDB, and Oracle into Amazon Redshift and Apache Iceberg-based data lakes. Shashank advises startups on technology strategy and mentors engineers and technical leaders at various career stages

    Five ways to use Kiro and Amazon Q to strengthen your security posture

    Post Syndicated from Roger Nem original https://aws.amazon.com/blogs/security/five-ways-to-use-kiro-and-amazon-q-to-strengthen-your-security-posture/

    A Monday morning security alert flags unauthorized access attempts, security group misconfigurations, and AWS Identity and Access Management (IAM) policy violations. Your team needs answers fast.

    Security teams are using Kiro and Amazon Q Developer to handle repetitive tasks—scanning resources, drafting policies, and researching Common Vulnerabilities and Exposures (CVEs)—so engineers can focus on risk decisions and complex scenarios that require human judgment, resulting in faster threat response and more consistent security coverage.

    This post shows you five ways to use Kiro and Amazon Q Developer to strengthen your AWS security posture based on the AWS Well-Architected Framework Security Pillar. Each technique builds on a common foundation described after the tool overview below.

    About these tools

    Amazon Web Services (AWS) gives customers choices when it comes to AI-assisted development and security automation. Whether you prefer Kiro’s agentic integrated development environment (IDE) experience or the deep integration of Amazon Q Developer into your existing AWS environment, both tools can help you implement the security practices described in this post. The right choice depends on your team’s workflow, and in many cases both tools are complementary and can be used together.

    Kiro is an AI-powered, agentic, IDE designed by AWS for specification-driven development, combining natural language prompting with structured, intentional coding to generate, test, and deploy applications.

    Amazon Q Developer is the generative AI assistant integrated into AWS development and cloud environments, designed to answer questions, generate code, troubleshoot issues, and automate operational tasks across AWS services.

    For setup instructions and to learn more, see the Kiro documentation and Amazon Q Developer documentation.

    1. Embed security best practices with persistent context

    Providing AI assistants with the right context helps them produce more consistent and relevant results. Each of the five techniques in this post becomes significantly more powerful when your AI assistant already understands your organization’s security standards. Setting up persistent context first means every subsequent interaction builds on that foundation, and the results you get from triage, remediation, reviews, and policy development will better reflect your specific environment rather than generic best practices.

    Without persistent context, you need to repeat the same security requirements in every prompt such as "enable encryption, use least privilege IAM settings, and enable logging," which leads to inconsistent results and missed controls. Amazon Q Developer IDE Plugin rules and Kiro steering files (CLI and IDE) solve exactly this problem: you can use them to codify your organization’s security standards so AI automatically builds secure infrastructure consistently, without requiring you to repeat requirements in every prompt. Both tools support this capability independently, so you can configure whichever fits your workflow, or use both together for coverage across your full development environment. The following steps show you how to get started with each.

    For Amazon Q Developer:

    1. Create directory: .amazonq/rules/ in your project root.
    2. Create file: .amazonq/rules/security-standards.md.
    3. Paste your organization’s security standards in natural language (see “Example security standards context file” below).

    For Kiro (steering files):

    In Kiro, persistent context documents are called steering files. They give the agent ongoing awareness of your architecture decisions, coding standards, and security requirements across every interaction and every session.

    1. Create file: security-standards.md in your project root.
    2. Reference it in prompts: Using security-standards.md as context, create....

    Pro tip: You can use Kiro itself to help you create steering files. Describe your security requirements in natural language and ask Kiro to generate a structured steering file for your review before saving and activating it. This means your AI assistant can help you build the very context it will later use, making the setup process faster and more thorough.

    Example security standards context file:

    # AWS Security Standards
    
    ## Identity and Access Management
    - All IAM roles must use least privilege principles
    - Require MFA for console access
    - Enable IAM Access Analyzer for all accounts
    - Rotate access keys every 90 days
    - Use IAM roles for EC2 instances, never embed access keys
    
    ## Data Protection
    - Enable encryption at rest for all storage services (S3, EBS, RDS)
    - Use AWS KMS customer-managed keys for sensitive data
    - Enable encryption in transit with TLS 1.2 minimum
    - Implement S3 bucket policies denying unencrypted uploads
    - Enable versioning and MFA delete for critical S3 buckets
    
    ## Infrastructure Protection
    - Security groups must follow least privilege (no 0.0.0.0/0 on sensitive ports)
    - Deploy resources in private subnets when possible
    - Enable VPC Flow Logs for network monitoring
    - Use AWS WAF for public-facing applications
    - Implement Network ACLs as additional defense layer
    
    ## Detective Controls
    - Enable CloudTrail in all regions with log file validation
    - Configure CloudWatch alarms for security events
    - Enable GuardDuty for threat detection
    - Set up AWS Config rules for compliance monitoring
    - Implement centralized logging with retention policies
    
    ## Incident Response
    - Create SNS topics for security alerts
    - Configure automated responses with AWS Lambda
    - Maintain runbooks for common security incidents
    - Enable AWS Systems Manager for secure instance access
    - Implement automated backup and recovery procedure

    What this unlocks:

    Without persistent context, a prompt like Create a Lambda function to process customer data could produce a basic function with no encryption, logging, or IAM configuration. AI output is non-deterministic, meaning that without guidance it might or might not include those controls. Steering files and rules documents minimize those variables by providing stronger guidance as part of every prompt and inference input.

    With your security standards embedded as in the example above, however, the same prompt generates a function with KMS-encrypted environment variables, a CloudWatch log group with 90-day retention, least-privilege IAM, VPC placement in private subnets, a dead-letter queue, and AWS X-Ray tracing—all automatically.

    Where it works:

    This persistent context approach applies across both tools and all infrastructure generation workflows:

    • Amazon Q Developer IDE Plugin: Rules in .amazonq/rules/ apply automatically to every code generation and review interaction.
    • Kiro: Steering files provide the agent with continuous architectural and security awareness across sessions and projects.

    The shift-left impact:

    This approach isn’t a replacement for your existing continuous integration and delivery (CI/CD) security automation. It’s a powerful complement to it, and that distinction matters. By embedding security standards directly into the development workflow, you shift security validation further left than pipeline checks can reach. Developers across your organization, not just security specialists, can generate infrastructure that meets your security standards from the first line of code. This scales security expertise into non-security roles, empowers development teams to self-serve on compliance requirements, and reduces the volume of findings that ever reach your automated pipeline checks.

    The result is security functioning as an enabler of faster development rather than a gate that slows it down, and security engineers spending their time on policy design and complex risk decisions rather than remediating avoidable misconfigurations.

    Measurable impact:

    Track these metrics to quantify the value of persistent context:

    • Security findings during code review: Establish a 30–60 day baseline before enabling context files, then compare
    • Time from development to deployment: Track average cycle time before and after
    • Remediation cost: Research consistently shows defects fixed in development cost significantly less than those fixed in production. Track your own ratio for 60 days
    • Standards consistency: Audit a random sample of infrastructure pull requests for compliance with your top 10 policies

    Implementation recommendation: Start by codifying your top 10 most frequently violated security policies as context. Measure the reduction in these specific findings over 30–60 days to quantify the impact on your team.

    2. Accelerate security finding triage and investigation

    AWS Security Hub consolidates findings from services such as Amazon GuardDuty, AWS Config, Amazon Inspector, and third-party security tools into a single dashboard, providing centralized security finding visibility and built-in triage capabilities across your AWS environment. AWS Security Hub Extended will bring even more capabilities into this mix, giving customers expanded control and additional opportunities to leverage the AI-assisted workflows described in this post at greater scale and with deeper integration across your security toolchain.

    Kiro can complement Security Hub by helping you correlate findings across accounts, understand CVE context, and develop remediation approaches, including:

    • Query findings using natural language across multiple AWS accounts and AWS Regions
    • Understand specific CVEs and their potential impact on your infrastructure
    • Generate investigation queries for AWS CloudTrail and Amazon Virtual Private Cloud (Amazon VPC) Flow Logs
    • Correlate security events across different time periods and services
    • Access the latest AWS security documentation and best practices

    How it works – Model Context Protocols:

    To enable these capabilities, Kiro uses Model Context Protocols (MCPs)—a standardized way for AI assistants to securely connect with external tools, services, and data sources, enabling them to take actions, retrieve real-time information, and interact with APIs beyond their built-in capabilities.

    Open source MCP servers for AWS are a suite of specialized MCP servers that enable Kiro to interact with AWS security services, providing real-time visibility into your security posture. To get started, configure security-focused MCP servers in your Kiro settings file (as shown in the following example). For full instructions on configuring MCP servers in Kiro, see the Kiro MCP documentation.

    Note on authentication: Before querying Security Hub, verify you have configured valid AWS credentials for the target account. Set the AWS_PROFILE value to a named profile in your ~/.aws/credentials file that has the appropriate permissions, or configure credentials using the AWS Command Line Interface (AWS CLI) (aws configure). Without valid credentials for the target account, Kiro will not be able to retrieve findings.

    {
        "mcpServers": {
            "awslabs.aws-api-mcp-server": {
                "command": "uvx",
                "args": ["awslabs.aws-api-mcp-server@latest"],
                "env": {
                    "FASTMCP_LOG_LEVEL": "ERROR",
                    "AWS_PROFILE": "<PROFILE>",
                    "AWS_REGION": "us-east-1"
                },
                "timeout": 120000,
                "disabled": false
            },
            "awslabs.cloudtrail-mcp-server": {
                "command": "uvx",
                "args": ["awslabs.cloudtrail-mcp-server@latest"],
                "env": {
                    "FASTMCP_LOG_LEVEL": "ERROR",
                    "AWS_PROFILE": "<PROFILE>"
                },
                "disabled": false
            },
            "awslabs.iam-mcp-server": {
                "command": "uvx",
                "args": ["awslabs.iam-mcp-server@latest"],
                "env": {
                    "FASTMCP_LOG_LEVEL": "ERROR",
                    "AWS_PROFILE": "<PROFILE>"
                },
                "disabled": false
            }
        }
    }

    Configure the following security-focused MCP servers to get started:

    • AWS API MCP Server: Interact with Security Hub, GuardDuty, IAM Access Analyzer, and AWS Config through AWS CLI commands
    • CloudTrail MCP Server: Audit trail analysis and compliance monitoring
    • AWS IAM MCP Server: Manage IAM users, roles, policies, and permissions
    • AWS Knowledge MCP Server: Access up-to-date AWS security documentation and best practices

    For a full list of available MCP servers, see the awslabs/mcp GitHub repository.

    Example: querying Security Hub with Kiro:

    1. Open your terminal or Kiro IDE.
    2. Enter the following command:
    "Show me all critical security findings from Security Hub in my production account ID <ACCOUNT ID>"

    Example output:

    > Found 4 critical security findings in account 123456789012:
    
    ## Configuration Issues (2)
    
    1. SSM.7 - SSM documents block public sharing disabled
    - Status: FAILED (since July 17, 2025)
    - Impact: Systems Manager documents can be publicly shared
    - Remediation: Enable block public sharing setting for SSM documents
    - [Documentation](https://docs.aws.amazon.com/console/securityhub/SSM.7/remediation)
    
    2. Config.1 - AWS Config not properly configured
    - Status: FAILED (since March 4, 2025)
    - Issue: Config isn't recording required IAM resource types (User, Role, Group, Policy)
    - Standards affected: CIS, NIST 800-53, PCI DSS, AWS Foundational Security
    - Remediation: Enable recording for IAM resources in AWS Config
    - [Documentation](https://docs.aws.amazon.com/console/securityhub/Config.1/remediation)
    
    ## Vulnerabilities (2)
    
    3. CVE-2020-36242 in Lambda function: MyLambdaOne
    - Package: cryptography version 3.2.1
    - CVSS Score: 9.1 (Critical)
    - Issue: Integer/buffer overflow in Fernet encryption class
    - Fix: Upgrade to cryptography 3.3.2
    - Function: SPC-1233HH5R-MyLambdaOne-lUh3ESH0MdXF
    
    4. CVE-2020-36242 in Lambda function: AutoUpdateMyLambdaOne
    - Package: cryptography version 3.2.1
    - CVSS Score: 9.1 (Critical)
    - Same vulnerability as above
    - Function: SPC-1233HH5R-AutoUpdateMyLambdaOne-d9HIBfxThbFW

    Real-world impact:
    Security finding triage that previously required navigating multiple consoles, correlating logs manually, and researching CVE databases can be accelerated significantly. Teams that have integrated AI-assisted triage into their Security Hub workflows report reducing mean time to triage for critical findings from hours to minutes, enabling faster containment and more consistent coverage across accounts.

    3. Accelerate remediation of security findings in your infrastructure as code

    AI assistants can scan your infrastructure code and flag security issues with specific fix recommendations. However, implementing these changes requires careful review, testing, and validation before any changes reach production.

    Important: AI-generated remediation suggestions must be reviewed by a qualified security engineer before implementation. Automated application of AI-generated changes without human validation can introduce unintended misconfigurations or service disruptions. Treat AI output as a starting point, not a finished product.

    The workflow:
    You can execute this workflow in either Kiro or Amazon Q Developer, depending on which tool fits your existing development environment:

    1. Ask Kiro or Amazon Q Developer to scan your infrastructure files and identify security gaps.
    2. Review AI-generated remediation suggestions with your security team.
    3. Test changes in non-production environments.
    4. Validate using AWS security services such as IAM Access Analyzer, AWS Config, and Security Hub.
    5. Deploy to production with monitoring and rollback procedures in place.

    Example prompt:

    "Scan my infrastructure at /path/to/templates, identify all S3 buckets without encryption, enable AES-256 encryption, add bucket policies to deny unencrypted uploads, and provide the deployment command"

    What happens:

    The AI assistant analyzes your infrastructure files, whether written in AWS CloudFormation, Terraform , or AWS Cloud Development Kit (AWS CDK), and identifies resources that violate security best practices. It then implements controls such as encryption at rest using AWS Key Management Service (AWS KMS) or Amazon Simple Storage Service (Amazon S3)-managed keys, adds bucket policies enforcing encryption in transit, configures public access blocks, and generates the exact deployment command with a change preview so you can review what will be modified before anything is applied.

    Based on the example security standards context file above, the following controls would be applied across all generated infrastructure: encryption at rest and in transit, least-privilege IAM policies, security group optimizations, VPC configurations, logging enablement, and backup and recovery settings.

    Validation required:
    AI-generated configurations deserve the same thoughtful review as other infrastructure code. Even a policy that looks correct on the surface might need tuning to match your organization’s least-privilege standards, or encryption settings might need adjusting to satisfy specific compliance requirements. Running those changes through a non-production environment and having a human confirm the results before anything reaches production are part of good infrastructure practices, whether the code was written by a person or generated by AI.

    Real-world impact:

    Identifying non-compliant resources across multiple accounts manually can take many hours and generating remediation templates for each resource can add significant time. Security teams that have adopted AI-assisted infrastructure scanning report spending less time on manual identification and template generation, and with AI assistance the same identification and drafting work can be completed in much less time. Customers report that a full remediation cycle that previously occupied their team for the better part of a day can be completed in under an hour when AI handles the scanning and template generation. It is worth noting that manual remediation time grows considerably at scale, as remediating dozens of non-compliant resources is not a linear exercise. Validation time in non-production environments remains essential regardless of how the remediation was generated, and should always be factored into your planning.

    4. Perform in-depth security reviews

    Amazon Q Developer and Kiro can analyze your infrastructure code and identify potential security issues across multiple categories aligned with the AWS Well-Architected Framework Security Pillar.

    Using Amazon Q Developer:

    1. Open your infrastructure file in your IDE.
    2. Select the code you want to review.
    3. Open the context menu and choose Send to Amazon Q, then choose Optimize.
    4. Select Focus on security best practices.

    Using Kiro:

    1. Open your infrastructure file in Kiro.
    2. Enter a natural language prompt such as: Perform a comprehensive security review of this CloudFormation template and identify all deviations from our standards.
    3. Kiro will automatically apply your steering files as additional context when generating its response.
    4. Review the findings and iterate with follow-up prompts.

    Security categories evaluated: For the complete, up-to-date list of security categories and controls, see the AWS Well-Architected Framework Security Pillar documentation. Current categories include but are not limited to:

    • Identity and access management: Overly permissive IAM policies, missing multi-factor authentication (MFA) requirements, unused credentials and access keys, cross-account access risks
    • Detective controls: CloudTrail logging configuration, Amazon CloudWatch alarm coverage, GuardDuty enablement status, and AWS Config rule implementation
    • Infrastructure protection: Security group misconfigurations, public subnet exposure, missing AWS WAF rules, unencrypted network traffic
    • Data protection: Storage encryption status, KMS key rotation policies, backup configurations, S3 bucket access controls
    • Incident response: Amazon Simple Notification Service (Amazon SNS) alerting setup, log retention policies, automated response mechanisms

    Example output:

    Security Recommendations:
    - Enable S3 bucket encryption with KMS: Critical
    - Implement least privilege IAM policies: High
    - Enable GuardDuty threat detection: High
    - Configure VPC Flow Logs: Medium
    - Add WAF rules for API Gateway: Medium
    - Enable CloudTrail in all regions: Critical
    - Implement automated backup policies: High
    
    Total security improvements: 23 findings across 5 Well-Architected pillars

    Keeping your configuration files current:

    A security architect review remains valuable for keeping your steering files and rules documents complete and current. The goal is an AI assistant that already understands your environment, not one that needs correcting after every interaction. Treat your configuration files as living documents and update them when your security standards evolve, when new services are adopted, or when post-incident reviews reveal gaps. As this post notes, project rules reduce architectural drift and help maintain consistency as AI agents operate more autonomously.

    Real-world impact:

    Security reviews that previously required a security engineer to manually inspect infrastructure templates line by line can be completed in significantly less time with AI assistance. Teams using AI-assisted security reviews as a pre-commit gate—before code reaches CI/CD pipeline checks—report catching a meaningful portion of security findings earlier in the development cycle where they are faster and less costly to address. Integrating this review step into pull request workflows means security validation happens continuously rather than only at deployment gates.

    5. Assist with service control policy development

    You can use AWS Organizations Service Control Policies (SCPs) to apply preventive controls consistently across every account in your organization, enforcing security baselines without relying on individual account administrators. Kiro can generate initial SCP drafts from natural language security requirements, speeding up the drafting and iteration process considerably. Because SCPs are preventive controls that can’t be bypassed by administrators, misconfigurations can cause organization-wide service disruptions, making expert validation and staged testing essential before any SCP reaches production.

    Step 1: Generate an SCP draft:

    Describe your security requirements in natural language:

    "Create an SCP with these security controls:
    - Deny creation of S3 buckets without encryption
    - Require MFA for IAM user console access
    - Prevent public RDS snapshots
    - Deny security group rules allowing 0.0.0.0/0 on sensitive ports
    - Enforce encryption for all EBS volumes
    - Require VPC Flow Logs on all VPCs
    - Deny IAM policy creation without approval tags
    - Restrict resource creation to approved regions only"

    Kiro generates a complete SCP policy JSON with proper deny statements, condition keys for MFA and encryption enforcement, resource-level restrictions, and regional compliance requirements.

    Step 2: Validate and lint the SCP:

    Use Kiro or Amazon Q Developer to assist with policy linting and initial testing as a first layer of validation. IAM Policy Autopilot, available as a Kiro Power with one-click installation directly from the Kiro IDE, can analyze your application’s usage and generate necessary permissions based on the SDK calls it discovers. IAM Policy Autopilot also integrates as an MCP server with Kiro, Amazon Q Developer, and other MCP-compatible coding assistants, making it a natural part of your existing workflow rather than a separate tool.

    "Review this SCP JSON for syntax errors, overly broad deny statements, and missing condition keys. Flag any statements that could unintentionally block legitimate operations."

    The IAM Policy Simulator then adds another layer of validation on top of the AI-assisted linting, so you can test policy behavior, verify condition keys are correctly applied, and confirm that no legitimate operations are unintentionally blocked. IAM Policy Autopilot complements existing IAM tools such as IAM Access Analyzer by providing functional policies as a starting point, which you can then validate using IAM Access Analyzer policy validation or refine over time with unused access analysis. Together, these tools form a layered validation approach where each one strengthens the output of the previous step.

    Step 3: Test in a sandbox environment:

    Create a test organizational unit (OU) with non-production accounts and apply the SCP to the test OU. Attempt operations that should be blocked and confirm that no legitimate operations are unintentionally blocked. Use Kiro to pre-validate your infrastructure code against the proposed SCP before sandbox testing:

    "Analyze my current infrastructure against this proposed SCP and identify resources that would be non-compliant"

    This scan covers your infrastructure code files. For live account scanning across your organization, use the following AWS services:

    • AWS Config with the Config Aggregator and Conformance Packs for continuous compliance monitoring across your organization.
    • IAM Access Analyzer for automated reasoning-based analysis of external access, internal access, and unused permissions.
    • Account Assessment for AWS Organizations for bulk scanning of identity-based, resource-based, and service control policies across all accounts.
    • Security Hub for centralized aggregation of compliance findings and security scores across your entire organization.

    Step 4: Security architect review:

    Engage your security architects to identify potential risks and verify the policy aligns with your security framework. Check for conflicts with existing SCPs by reviewing all SCPs attached to parent OUs and the root in the AWS Organizations console. Use the IAM Policy Simulator to test interactions between policies and verify that emergency access procedures ( SEC03-BP03 Establish emergency access process – Security Pillar and SEC10-BP05 Pre-provision access – Security Pillar) remain functional before any production rollout.

    Step 5: Staged rollout:

    Deploy to development accounts first and monitor for policy violations and operational issues. Gradually expand to additional environments and maintain documented rollback procedures throughout the process.

    Important: It’s strongly recommended not to deploy AI-generated SCPs directly to production without thorough expert review and staged testing. A misconfigured SCP can cause organization-wide service disruptions affecting every account in your organization.

    Real-world impact:

    SCP drafting that previously required security architects to write and iterate on complex JSON policy documents manually, often spanning multiple review cycles over several days, can be condensed when AI handles the initial drafting and linting. Your architects can then focus their time on policy design, edge case analysis, and organizational impact assessment rather than JSON syntax and structure.

    Responsible implementation framework

    Adopting AI-assisted security workflows is most effective when introduced gradually, with clear validation gates at each stage. The following two-phase approach gives your team time to build confidence, measure results, and establish the internal practices needed before expanding to production environments.

    • Phase 1: Development and testing (weeks 1–4): Start by testing AI-generated security controls in isolated development accounts. Validate functionality, identify edge cases, and deploy to a dedicated testing environment with thorough security validation. Use IAM Access Analyzer, AWS Config, and Security Hub to verify that generated controls behave as expected. This phase is also the right time to build internal expertise across both your security team and your development teams, so that knowledge of what works and what requires human review is shared broadly from the start.
    • Phase 2: Staging and production (week 5 and later): Apply the validated controls to a staging environment that mirrors production. Conduct penetration testing where appropriate and validate that monitoring and alerting function correctly before expanding further. Gradually roll out to production accounts with continuous monitoring in place. Maintain rollback procedures throughout and establish feedback loops so that lessons learned in production flow back into your steering files, rules documents, and validation processes over time.

    Key takeaways

    What distinguishes the approach in this post from general guidance on AI coding assistants is the specificity of the security integration. There’s no shortage of content about how AI assistants accelerate development. What this post focuses on is how to configure both Kiro and Amazon Q Developer to perform security-specific tasks: triaging findings from Security Hub, remediating infrastructure code vulnerabilities against your organization’s defined standards, conducting Well-Architected security reviews, drafting and validating SCPs, and generating secure-by-default infrastructure through persistent context that reflects your environment rather than generic defaults.

    Kiro is an agentic IDE that helps you go from prototype to production with spec-driven development, and its steering files give the agent persistent awareness of your security standards across every session. Amazon Q Developer complements this by providing deep integration into your existing AWS environment and IDE workflows. Together, these tools extend your security team’s reach into every stage of the development lifecycle, scale security expertise into development teams, and reduce the gap between when vulnerabilities are introduced and when they are caught. As the AWS Well-Architected Framework Security Pillar establishes, embedding security early and consistently across the development process is foundational to a strong security posture.

    These five techniques aren’t about replacing your security controls. They’re about making security a natural part of how your teams build on AWS, regardless of whether they’re security specialists or application developers. In addition to the five techniques covered in this post, the following AWS capabilities complement this approach and are worth exploring for a more complete picture:

    • Amazon Inspector is a vulnerability management service that continually scans AWS workloads for software vulnerabilities, code vulnerabilities, and unintended network exposure. It automatically discovers and scans Amazon EC2 instances, container images in Amazon ECR, AWS Lambda functions, and first-party code repositories. Amazon Inspector integrates directly into CI/CD pipelines through plugins for Jenkins, TeamCity, GitHub Actions, and Amazon CodeCatalyst, which teams can use to catch vulnerabilities before deployment. Its code security capabilities include Static Application Security Testing (SAST), Software Composition Analysis (SCA), and infrastructure as code (IaC) scanning, with native integration to GitHub and GitLab. All findings are surfaced directly in Security Hub for centralized visibility and response across your organization.
    • Amazon Q Developer security scanning provides real-time security issue detection in the IDE, including SAST scanning for security vulnerabilities, secrets detection, IaC security evaluation, and software composition analysis for third-party dependencies. These capabilities are available across JetBrains, Visual Studio Code, and Visual Studio.
    • Kiro Powers are curated and pre-packaged MCP servers, steering files, and hooks validated by Kiro partners to accelerate specialized development and deployment use cases. Security-relevant Kiro Powers include the IAM Policy Autopilot Kiro Power for baseline IAM policy generation and the real-time coding security validation MCP server pattern for Kiro.
    • AWS Security Agent is a frontier AI agent that proactively secures your applications throughout the development lifecycle. Security teams define organizational security requirements once in the AWS Security Agent console, such as approved encryption libraries, authentication frameworks, and logging standards, and AWS Security Agent then automatically validates these requirements throughout development by evaluating architectural documents and code against your defined standards. It provides three core capabilities: design security review for architecture documents, code security review that automatically analyzes pull requests against your defined standards across connected repositories, and on-demand penetration testing that discovers, validates, and reports vulnerabilities through sophisticated multi-step attack scenarios customized for each application. When vulnerabilities are found, AWS Security Agent creates pull requests with ready-to-implement fixes directly in your code repository. Customers report that AWS Security Agent compresses penetration testing timelines from weeks to hours, transforming penetration testing from a periodic bottleneck into an on-demand capability that reduces risk exposure and scales security reviews to match development velocity.
    • AWS Security Hub automated response and remediation provides pre-built playbooks for common findings using AWS Systems Manager Automation, enabling your team to act on findings faster and more consistently.

    Getting started

    If you’re new to AI-assisted security workflows, the following week-by-week approach gives your team a practical path forward without overextending before the foundation is in place.

    • Weeks 1 and 2: Set up your persistent context files with your top 10 security policies as described in the foundational setup section above. Configure MCP servers in Kiro for Security Hub and CloudTrail access and verify that credentials are correctly configured for your target accounts.
    • Weeks 3 and 4: Run your first AI-assisted security review on a non-production infrastructure template. Compare the findings against your last manual review to establish a baseline for measuring impact over time.
    • Weeks 5 and 6: pilot AI-assisted SCP drafting for one new preventive control. Run the full validation workflow including AI-assisted linting, IAM Policy Autopilot, and the IAM Policy Simulator before any production application.
    • From that point forward: Measure the metrics outlined in the foundational setup section, update your steering files and rules documents as your standards evolve, and share findings across your security team, development teams, and platform engineering teams. The knowledge of what works and what requires human judgment is valuable to everyone who touches infrastructure in your organization.

    Conclusion

    Kiro and Amazon Q Developer give security teams practical tools to accelerate threat response and maintain consistent security coverage by handling the tasks that consume the most time with the least strategic value: scanning for known misconfigurations, drafting policy JSON, researching CVEs, and generating secure infrastructure. These AI assistants are most effective when paired with security engineers, as they accelerate assessments and code generation while human review, policy design, and risk judgment remain essential throughout.

    By implementing the five techniques outlined in this post, starting with embedding security best practices through persistent context and then applying that foundation to Security Hub finding triage, infrastructure code remediation, in-depth Well-Architected security reviews, and SCP development, your team can strengthen your AWS security posture while maintaining the standards your organization requires.

    AWS services such as Security Hub, IAM Access Analyzer, AWS Config, and CloudTrail provide the foundation for these AI-assisted workflows, enabling centralized visibility and automated validation of security controls across your environment. Emergency access procedures should be established and validated before deploying any preventive controls such as SCPs, following the break-glass guidance in the AWS Well-Architected Security Pillar and the AWS Prescriptive Guidance for break-glass access.

    Start small with non-production environments, establish clear validation processes, measure results, and gradually expand your use of AI assistants as your team builds expertise and confidence. The result is faster threat response, more consistent security coverage, and security engineers focused on complex decisions rather than repetitive tasks.

    Additional resources

    If you have feedback about this post, submit comments in the Comments section below


    Roger Nem

    Roger Nem

    Roger is an Enterprise Technical Account Manager (TAM) supporting Healthcare & Life Science customers at Amazon Web Services (AWS). As a Security Technical Field community specialist, he helps enterprise customers design secure cloud architectures aligned with industry best practices. Beyond his professional pursuits, Roger finds joy in quality time with family and friends, nurturing his passion for music, and exploring new destinations through travel.

    Access control with IAM Identity Center session tags

    Post Syndicated from Rashmi Iyer original https://aws.amazon.com/blogs/security/access-control-with-iam-identity-center-session-tags/

    As organizations expand their Amazon Web Services (AWS) footprint, managing secure, scalable, and cost-efficient access across multiple accounts becomes increasingly important. AWS IAM Identity Center offers a centralized, unified solution for managing workforce access to AWS accounts. It simplifies authentication, enhances security, and provides a seamless user sign-in experience to AWS services across diverse environments.

    By combining IAM Identity Center permission sets with session tags, organizations can unlock powerful capabilities for fine-grained access control and resource optimization. You can use session tags to pass dynamic attributes from your external identity provider into AWS, enabling more context-aware permissions and better cost visibility. This integration makes it possible to use advanced AWS features such as AWS Glue usage profiles and AWS Systems Manager Session Manager run as to enforce fine-grained access control, so that administrators can dynamically map permissions and runtime configurations based on user attributes passed during federated access.

    In this post, I demonstrate how session tags derived from directory group attributes in Microsoft Entra ID can deliver functionality equivalent to AWS Identity and Access Management (IAM) role tags. Using role tags, you can implement attribute-based access control (ABAC) using IAM Identity Center, while maintaining centralized and efficient access management. To demonstrate this, you can configure an AWS Glue usage profile, as described in Introducing AWS Glue usage profiles for flexible cost control, where session tags can be passed through Identity Center and an external identity provider like Microsoft Entra ID. This approach is extensible to other AWS services such as AWS Systems Manager Session Manager (run as) and can also be used with other identity providers.

    User authentication and IAM Identity Center Federation flow

    The following figure shows the architecture and workflow of the solution.

    Figure 1 – User authentication and federation flow between Microsoft Entra and AWS

    Figure 1 – User authentication and federation flow between Microsoft Entra and AWS

    The user authentication and federation flow includes the following steps:

    1. User accesses application using a browser.
    2. The enterprise application (configured in Azure) initiates authentication.
    3. Microsoft Entra ID handles sign-in.
    4. Users and groups are managed in Entra ID.
    5. A SAML trust is established between Entra ID and IAM Identity Center.
    6. SCIM provisioning syncs users and groups from Entra ID to AWS.
    7. Synced users and groups appear in Identity Center.
    8. Session tags are passed during SAML authentication.
      • Entra ID can send user attributes (department, role, cost center, project ID, and so on) as SAML attributes.
      • Identity Center consumes these as session tags, which are used for fine-grained access control and attribute-based access control inside AWS.
    9. Admins define permission sets for users and groups in Identity Center.
    10. Users get federated access to AWS using their Entra ID credentials.
    11. Users sign in through AWS Management Console or AWS Command Line Interface (AWS CLI) using those permissions.
    12. Access is granted to specific AWS accounts under AWS Organizations.

    Prerequisites

    To follow the steps in this post, you need the following prerequisites:

    1. An organization instance of IAM Identity Center enabled.
    2. A Microsoft Entra ID tenant. For more information, see Quickstart: Create a new tenant in Microsoft Entra ID.
    3. Access to an external identity provider such as Microsoft Entra ID to federate users into AWS. You can enable federated access between Microsoft Entra ID and IAM Identity Center by completing the steps in Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center. They include configuring SAML and SCIM integration between the two systems, testing the SAML connection to help ensure authentication is functioning correctly, and enabling SCIM synchronization to automate user and group provisioning.

    Solution implementation

    With the prerequisites in place, you’re ready to configure access control through IAM Identity center tags by using the following steps.

    1. Create an AWS Glue usage profile as described in Introducing AWS Glue usage profiles for flexible cost control in Create an AWS Glue usage profile. For the purposes of this post, create a profile named developer.
      1. On the AWS Management Console for AWS Glue, choose Cost management in the navigation pane.
      2. Choose Create usage profile.
      3. For Usage profile name, enter developer.
      4. Under Customize configurations for jobs, for Number of workers, for Default, enter 20.
      5. For Default worker type, select G.1X.
      6. For Allowed worker types, select G.1X, G.2X, G.4X, and G.8X.
      7. For Customize configurations for sessions, configure the same values.
      8. Choose Create usage profile.
      Figure 2 – Glue usage profile creation on the console

      Figure 2 – Glue usage profile creation on the console

    2. Create a custom permission set instead of using predefined ones. Attach the following AWS Managed Policies to the custom permission set:
      • AWSGlueConsoleFullAccess
      • IAMReadOnlyAccess

      Note: For fine-grained access control, you can create custom permission sets by combining AWS managed, customer managed, and inline policies in IAM. In this post, you use AWS managed policies with intentionally broad permissions for simplicity. In production, always follow the principles of least privilege and scope permissions appropriately.

      By default, when you create a permission set, the permission set isn’t provisioned (used in any AWS accounts). To provision a permission set in an AWS account, you must assign IAM Identity Center access to users or groups in the account and then apply the permission set to those users and groups. For more information, see Assign user or group access to AWS accounts.

    3. Configure user attributes in Microsoft Entra ID for access control in IAM Identity Center as described in Step 5 of Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center to set up ABAC. Add claim conditions for attribute mapping based on Entra ID group membership. Assign the developer value for users in a corresponding group. This enables logic such as Users in this group receive this profile or All users receive this profile. When using an AWS Glue profile and when making API calls to create AWS Glue resources, admins need to tag the user or role with glue:UsageProfile as the key and the profile name as the value.
    4. Next, sign in to the enterprise application that you created in the previous step, which has SCIM and SAML connections set up to IAM Identity Center:
      1. Sign in to Azure.
      2. Choose Enterprise applications.
      3. Select the application that you created
        Figure 3 – An enterprise application created in Microsoft Entra ID

        Figure 3 – An enterprise application created in Microsoft Entra ID

    5. When you’re signed in to your application, select Manage and then Single sign-on in the navigation pane, then select Attributes & Claims.
      Figure 4 – Attributes & Claims section in Microsoft Entra ID

      Figure 4 – Attributes & Claims section in Microsoft Entra ID

    6. Configure the key value pair that will used as session tags by selecting Add new claim.
      Figure 5 – Configuring attributes by adding a new claim

      Figure 5 – Configuring attributes by adding a new claim

    7. For Name, enter AccessControl:<AttributeName>. Replace <AttributeName> with the name of the attribute you are expecting in IAM Identity Center. For this example, use AccessControl:glue:UsageProfile.
    8. In Claim conditions set the following:
      • User type, select Members
      • Source, select Attribute.
      • Value, enter developer (without quotation marks).
      Figure 6 – Attribute claim addition in Microsoft Entra using group membership

      Figure 6 – Attribute claim addition in Microsoft Entra using group membership

    It’s important to note that the tags are being assigned based on group membership in Microsoft Entra ID. This approach lets you manage access and configuration dynamically without needing to set tags individually for each user. By assigning the tag to a Microsoft Entra ID group, anyone signing in to IAM Identity Center and who is in that group will automatically have the tag value applied to their session.

    Test the solution

    Now that the required configuration is complete, test the setup using the developer usage profile created as part of the Solution implementation section. Sign in as your user through Microsoft Entra ID using https://myapps.microsoft.com/ and verify the job creation using the following steps mentioned.

    To verify successful job creation:

    1. Open the AWS Glue console using the developer usage profile.
    2. In the navigation pane, choose ETL jobs.
    3. Select Script editor, then choose Create script.
    4. Create a new job using the values you want to validate.

    The green banner at the top of the screen should say Successfully updated job.

    Figure 7 – Successful AWS Glue job creation with configured parameters for the <em>developer</em> usage profile” width=”678″ height=”864″ class=”size-full wp-image-41907″></p>
<p id=Figure 7 – Successful AWS Glue job creation with configured parameters for the developer usage profile
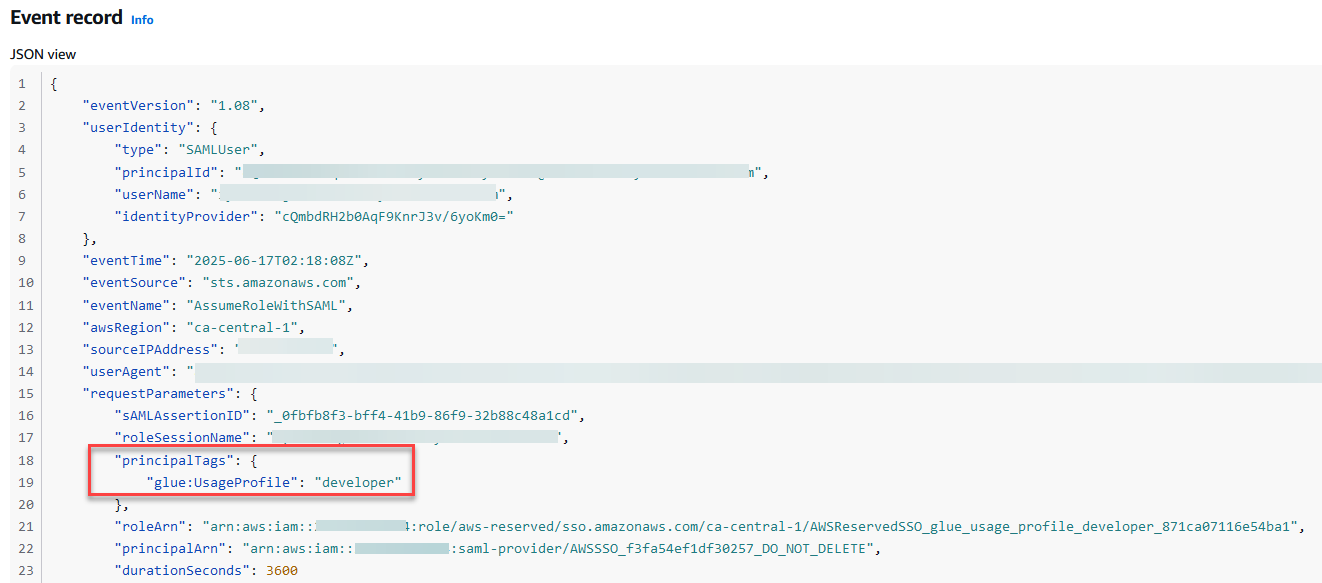
    Validation using AWS CloudTrail

    Examine the AssumeRoleWithSAML event using AWS Cloudtrail. Use the following steps to verify the sequence of events.

    1. Navigate to the CloudTrail console.
    2. Select Event history.
    3. In the Lookup attributes dropdown, select Event name.
    4. Set the event name to AssumeRoleWithSAML.
    5. Open a relevant event and inspect the requestParameters section.
    6. Confirm that the expected session tags appear under PrincipalTags.
    Figure 8 – ABAC tags passed during the role assumption

    Figure 8 – ABAC tags passed during the role assumption

    Using session tags for other use cases

    The concepts discussed in this post can be extended to configure AWS Systems Manager Session Manager Run As support for federated users using session tags. By default, Session Manager launches sessions using a system-generated ssm-user account. For Linux instances, you can optionally configure sessions to run as a specific OS-level user through Session Manager preferences. You can configure your identity provider to pass the user attribute (AccessControl: SSMSessionRunAs and name of an OS user account for the key value during federation and the session will be tagged using the attribute value.

    Clean up

    To avoid incurring future charges, delete any resources created during this walkthrough if they’re no longer needed:

    1. Remove the IAM Identity Center instance and clean up the associated enterprise application in Microsoft Entra.
    2. Delete the AWS Glue usage profile.
    3. Remove any other AWS resources you provisioned for testing the solution.

    Conclusion

    In this post, you learned how to federate access to AWS using AWS IAM Identity Center and SAML 2.0 identity providers like Microsoft Entra ID, enabling a secure, scalable, and centralized approach to managing user access across multiple AWS accounts. By using permission sets, reserved IAM roles, and session tags, organizations can implement fine-grained ABAC without the complexity of managing individual IAM users or static roles.

    As cloud environments become more complex, adopting modern identity federation and ABAC through IAM Identity Center helps security teams maintain control while providing users with seamless, context-aware access to the resources they need.

    Resources

    If you have feedback about this post, submit comments in the Comments section below.

    Rashmi Iyer

    Rashmi Iyer

    Rashmi is a Senior Solutions Architect at AWS, supporting financial services enterprises in building secure, resilient, and scalable cloud architectures while ensuring compliance with industry best practices. With over 15 years of experience in the private telco cloud, she has designed and architected complex telecom solutions, specializing in the packet core domain, the backbone of mobile data networks.

    Using Apache Sedona with AWS Glue to process billions of daily points from a geospatial dataset

    Post Syndicated from Ruan Roloff original https://aws.amazon.com/blogs/big-data/using-apache-sedona-with-aws-glue-to-process-billions-of-daily-points-from-a-geospatial-dataset/

    Data strategy can use geospatial data to provide organizations with insights for decision-making and operational optimization. By incorporating geospatial data (such as GPS coordinates, points, polygons and geographic boundaries), businesses can uncover patterns, trends, and relationships that might otherwise remain hidden across multiple industries, from aviation and transportation to environmental studies and urban planning. Processing and analyzing this geospatial data at scale can be challenging, especially when dealing with billions of daily observations.

    In this post, we explore how to use Apache Sedona with AWS Glue to process and analyze massive geospatial datasets.

    Introduction to geospatial data

    Geospatial data is information that has a geographic component. It describes objects, events, or phenomena along with their location on the Earth’s surface. This data includes coordinates (latitude and longitude), shapes (points, lines, polygons), and associated attributes (such as the name of a city or the type of road).

    Key types of geospatial geometries (and examples of each in parentheses) include:

    • Point – Represents a single coordinate (a weather station).
    • MultiPoint – A collection of points (bus stops in a city).
    • LineString – A series of points connected in a line (a river or a flight path).
    • MultiLineString – Multiple lines (multiple flight routes).
    • Polygon – A closed area (the boundary of a city).
    • MultiPolygon – Multiple polygons (national parks in a country).

    Geospatial datasets come in different formats, each designed to store and represent different types of geographic information. Common formats for geospatial data are vector formats (Shapefile, GeoJSON), raster formats (GeoTIFF, ESRI Grid), GPS formats (GPX, NMEA), web formats (WMS, GeoRSS) among others.

    Core concepts of Apache Sedona

    Apache Sedona is an open-source computing framework for processing large-scale geospatial data. Built on top of Apache Spark, Sedona extends Spark’s capabilities to handle spatial operations efficiently. At its core, Sedona introduces several key concepts that enable distributed spatial processing. These include Spatial Resilient Distributed Datasets (SRDDs), which allow for the distribution of spatial data across a cluster, and Spatial SQL, which provides a familiar SQL-like interface for spatial queries. Some of the core capabilities of Apache Sedona are:

    • Efficient spatial data types like points, lines and polygons.
    • Spatial operations and functions such as ST_Contains (check if point is inside of a polygon), ST_Intersects (check if point is inside of a polygon), ST_H3CellIDs (geospatial indexing system developed by Uber, return the H3 cell ID(s) that contain the given point at the specified resolution).
    • Spatial joins to combine different spatial datasets.
    • Integration with Spark SQL (geospatial functions to run spatial SQL queries).
    • Spatial indexing techniques, such as quad-trees and R-trees, to optimize query performance.

    For more information about the functions available in Apache Sedona, visit the official Sedona Functions documentation.

    Use case

    This use case consists of a global air traffic visualization and analysis platform that processes and displays real-time or historical aircraft tracking data on an interactive world map. Using unique aircraft identifiers from the International Civic Aviation Organization (ICAO), the system ingests trajectory records containing information such as geographic position (latitude and longitude), altitude, speed, and flight direction, then transforms this raw data into two complementary visual layers. The Flight Tracks Layer plots the routes traveled by each aircraft individually, allowing for the analysis of specific trajectories and navigation patterns. The Flight Density Layer uses hexagonal spatial indexing (H3) to aggregate and identify regions of higher air traffic concentration worldwide, revealing busy air corridors, aviation hubs, and high-density flight zones.

    The dataset used for this use case is historical flight tracker data from ADSB.lol. ADSB.lol provides unfiltered flight tracker with a focus on open data. Data is also freely available via the API. The data contains a file per aircraft, a JSON gzip file containing the data for that aircraft for the day.

    This is a JSON trace file format sample:

    {
        icao: "0123ac", // hex id of the aircraft
        timestamp: 1609275898.495, // unix timestamp in seconds since epoch (1970)
        trace: [
            [ seconds after timestamp,
                lat,
                lon,
                altitude in ft or "ground" or null,
                ground speed in knots or null,
                track in degrees or null, (if altitude == "ground", this will be true heading instead of track)
                flags as a bitfield: (use bitwise and to extract data)
                    (flags & 1 > 0): position is stale (no position received for 20 seconds before this one)
                    (flags & 2 > 0): start of a new leg (tries to detect a separation point between landing and takeoff that separates flights)
                    (flags & 4 > 0): vertical rate is geometric and not barometric
                    (flags & 8 > 0): altitude is geometric and not barometric
                 ,
                vertical rate in fpm or null,
                aircraft object with extra details or null,
                type / source of this position or null,
                geometric altitude or null,
                geometric vertical rate or null,
                indicated airspeed or null,
                roll angle or null
            ],
        ]
    }

    For this use case, this is a simplified schema of the dataset after processing:

    • icao - Unique aircraft identifier
    • timestamp - Epoch timestamp of the observation (converted to readable format)
    • trace.lat / trace.lon - Latitude and longitude of the aircraft
    • trace.altitude - Aircraft altitude
    • trace.ground_speed - Ground speed
    • geometry - Geospatial geometry of the observation point (Point)

    Solution overview

    This solution enables aircraft tracking and analysis. The data can be visualized on maps and used for aviation management and safety applications. The process begins with data acquisition, extracting the compressed JSON files from TAR archives, then transforms this raw data into geospatial objects, aggregating them into H3 cells for efficient analysis. The processed data schema includes ICAO aircraft identifiers, timestamps, latitude/longitude coordinates, and derived fields such as H3 cell identifiers and point counts per cell. This structure allows detailed tracking of individual flights and aggregate analysis of traffic patterns. For visualization, you can generate density maps using the H3 grid system and create visual representations of individual flight tracks. The architecture data flow is as follows:

    • Data ingestion – Aircraft observation data stored as JSON compressed files in Amazon Simple Storage Service (Amazon S3).
    • Data processing – AWS Glue jobs using Apache Sedona for geospatial processing.
    • Data visualization – Spark SQL with Sedona’s spatial functions to extract insights and export data to visualize the information in a map on Kepler.gl.

    The following figure illustrates this solution.

    AWS architecture diagram showing a geospatial data processing pipeline.

    Prerequisites

    You will need the following for this solution:

    Solution walkthrough

    From now on, executing the next steps will incur costs on AWS. This step-by-step walkthrough demonstrates an approach to processing and analyzing large-scale geospatial flight data using Apache Sedona and Uber’s H3 spatial indexing system, using AWS Glue for distributed processing and Apache Sedona for efficient geospatial computations. It explains how to ingest raw flight data, transform it using Sedona’s geospatial functions, and index it with H3 for optimized spatial queries. Finally, it also demonstrates how to visualize the data using Kepler.gl. For data processing, it is possible to use both Glue scripts and Glue notebooks. In this post, we will focus only on Glue scripts.

    Upload the Apache Sedona libraries to Amazon S3

    1. Open your OS terminal command line.
    2. Create a folder to download the Sedona libraries and name it jar.
      
      	# Create a directory for the Sedona libraries (JARs files)
      	mkdir jar
      	# Go to the folder JARs folder
      	cd jar
      	
    3. Download the Apache Sedona libraries.
      
      	# Download required Sedona libraries (JARs files)
      	wget https://repo1.maven.org/maven2/org/apache/sedona/sedona-spark-shaded-3.5_2.12/1.7.1/sedona-spark-shaded-3.5_2.12-1.7.1.jar
      	wget https://repo1.maven.org/maven2/org/datasyslab/geotools-wrapper/1.7.1-28.5/geotools-wrapper-1.7.1-28.5.jar
      	
    4. Upload the Sedona libraries (JARs files) to Amazon S3. In this example, we use the S3 path s3://aws-blog-post-sedona-artifacts/jar/.
      
      	# Upload the JARs files to Amazon S3 bucket
      	aws s3 cp . s3://blog-sedona-artifacts-<account_number>-<aws_region>/jar/ --recursive
      	
    5. Your Amazon S3 folder should now look similar to the following image:

    Amazon S3 console screenshot displaying the jar folder contents in blog-sedona-artifacts bucket.

    Download and upload the geospatial data to Amazon S3

    1. Open your OS terminal command line.
    2. Create a folder to download the flight files and name it adsb_dataset.
      		# Create a directory for download the geospatial flight files
      		mkdir adsb_dataset
      		# Go to the folder for geospatial flight files
      		cd adsb_dataset
      	
    3. Download the flight files data from adsblol GitHub repository.
      	# Download the geospatial flight files in the folder created
      	wget https://github.com/adsblol/globe_history_2025/releases/download/v2025.05.29-planes-readsb-prod-0tmp/v2025.05.29-planes-readsb-prod-0tmp.tar.aa
      	wget https://github.com/adsblol/globe_history_2025/releases/download/v2025.05.29-planes-readsb-prod-0tmp/v2025.05.29-planes-readsb-prod-0tmp.tar.ab
      	
    4. Extract the flight files.
      	# Combine the two the tar files together
      	cat v2025.05.29* >> combined.tar
      	# Extract the json flight files from the tar file
      	tar xf combined.tar
      	
    5. Copy the flight files to Amazon S3. In this case, we are using the S3 folder: s3://blog-sedona-nessie-<account_number>-<aws_region>/raw/adsb-2025-05-28/traces/.
      	# Copy the json flight files to Amazon S3
      	aws s3 cp ./traces/ s3://blog-sedona-nessie-<account_number>-<aws_region>/raw/adsb-2025-05-28/traces/ --recursive
      	
    6. Your Amazon S3 folder should now look similar to the following image.

    Amazon S3 console showing JSON trace files in the path raw/adsb-2025-05-28/traces/00/.

    Create an AWS Glue job and set up the job

    Now, we are ready to define the AWS Glue job using Apache Sedona to read the geospatial data files. To create a Glue job:

    1. Open the AWS Glue console.
    2. On the Notebooks page, choose Script editor.

    AWS Glue Studio jobs creation interface showing three job creation methods: Visual ETL with data flow interface, Notebook for interactive coding, and Script editor for code authoring

    1. On the Script screen, for the engine, choose Spark, then select the option Upload script.
    2. Choose Choose file. Find the process_sedona_geo_track.py file, then choose Create script.

    Script creation dialog box with Spark engine selected. Upload script option is active, showing successfully uploaded file process_sedona_geo_track.py.

    1. Rename the job from Untitled to process_sedona_geo_track.
    2. Choose Save.
    3. Now, let’s set up the AWS Glue job. Choose Job Details.
    4. Choose the IAM Role created to be used with Glue. For this example, we use blog-glue.
    5. Set the Glue version to Glue 5.0 and the Worker type as needed. For this example, G.1X is sufficient, but we use G.2X to speed up processing.

    AWS Glue job details configuration page for process_sedona_geo_track.

    1. Now, let’s import the libraries for Apache Sedona.
    2. In the Dependent JARs path, type the path of the JAR files for Apache Sedona that you uploaded in the preceding steps. For this example, we used s3://blog-sedona-artifacts-<account_number>-<aws_region>/jar/sedona-spark-shaded-3.5_2.12-1.7.1.jar,s3://blog-sedona-artifacts-<account_number>-<aws_region>/jar/geotools-wrapper-1.7.1-28.5.jar
    3. In Additional Python modules path, enter the modules for Apache Sedona: apache-sedona==1.7.1,geopandas==0.13.2,shapely==2.0.1,pyproj==3.6.0,fiona==1.9.5,rtree==1.2.0

    ob libraries configuration section showing Dependent JARs path pointing to S3 bucket.

    1. In the Job parameters section, in the Key field, type —BUCKET_NAME. For its Value, enter your bucket name. In this example, ours is blog-sedona-nessie-<account_number>-<aws_region>.

    ob parameters configuration interface showing key-value pair with --BUCKET_NAME parameter.

    1. Choose Save.

    Processing the geospatial flights data

    Before we run the job, let’s understand how the code works. First, import the Apache Sedona libraries:

    import json 
    import gzip 
    from sedona.spark import SedonaContext

    Next, initialize the Sedona context using an existing Spark session:

    sedona = SedonaContext.create(spark)

    After that, create a function for handling compressed JSON data:

    def parse_gzip_json(byte_content):
            try:
                decompressed = gzip.decompress(byte_content)
                return json.loads(decompressed.decode('utf-8'))
            except Exception as e:
                print(f"Error during gzip parse: {str(e)}")
                return None

    Add a function to transform raw tracking data into a structured format suitable for a valid coordinates process:

    def flatten_records(json_obj):
        records = []
        if "trace" in json_obj and isinstance(json_obj["trace"], list):
            for point in json_obj["trace"]:
                if len(point) >= 3:
                    lat, lon = float(point[1]), float(point[2])
                    if -90 <= lat <= 90 and -180 <= lon <= 180:
                        records.append(Row(
                            icao=json_obj.get("icao", None),
                            timestamp=json_obj.get("timestamp", None),
                            lat=lat,
                            lon=lon
                        ))
        return records

    The flat_rdd variable applies these functions to the structured data from the original gzipped JSON. Each element in this RDD is a Row object representing a single data point from an aircraft’s trace, with fields for ICAO, timestamp, latitude, and longitude.

    flat_rdd = raw_rdd.map(lambda x: parse_gzip_json(x[1])).filter(lambda x: x is not None).flatMap(flatten_records)

    The ADSB trace files contain a deeply nested JSON structure where the trace field holds an array of mixed-type arrays, compressed in Gzip format. For this specific case, developing a UDF represented one of the most practical and efficient solutions. Since Gzip is a non-splittable format, Spark is unable to parallelize processing, constraining both methods to a single worker per file and processing the data multiple times across JVM decompression, full JSON parsing, and subsequent re-parsing operations. The UDF bypasses all of this by reading raw bytes and doing everything in a single Python pass: decompress → parse → extract → validate, returning only the small set of needed fields directly to Spark.

    The Spark SQL query processes geographic trace data using the H3 hexagonal grid system, converting point data into a regularized hexagonal grid that can help identify areas of high point density. A resolution of 5 was adopted, producing hexagons of approximately 253 km² (roughly the same size as the city of Edinburgh, Scotland, which is approximately 264 km²), for its ability to effectively capture route density patterns at the city and metropolitan level.

    h3_traces_df = spark.sql("""
    WITH base_h3 AS (
        SELECT
            ST_H3CellIDs(geometry, 5, false)[0] AS h3_index,
            lat,
            lon
        FROM traces
    )
    SELECT
        COUNT(*) AS num, -- Count points in each H3 cell
        h3_index,
        AVG(lon) AS center_lon,
        AVG(lat) AS center_lat
    FROM base_h3
    GROUP BY h3_index
    """)
    

    Finally, this code prepares the datasets for visualization purposes. The first dataset is based on the aircraft unique identifier. The complete dataset for a single day can contain more than 80 million data points. A random sampling rate of 0.1% was applied, which proves sufficient to illustrate route density patterns without overwhelming the Kepler.gl browser renderer. The second dataset aggregates trace points into hexagonal spatial cells (result from the query above).

    points_viz_sampled = df_points.select(
        col("icao"), # Aircraft unique identifier (24-bit address)
        col("timestamp").cast("double").alias("timestamp"),
        col("lat").cast("double").alias("lat"),
        col("lon").cast("double").alias("lon")
    ).sample(False, 0.001)
    
    h3_viz_csv = h3_traces_df.select(
        col("num").alias("point_count"),
        col("h3_index").cast("string").alias("h3_index"),
        col("center_lon"),
        col("center_lat")
    )

    Now that we understand the code, let’s run it.

    1. Open the AWS Glue console.
    2. On the ETL jobs >> Notebooks page, choose the job name process_sedona_geo_track.
    3. Choose Run.

    Python script editor showing import statements for process_sedona_geo_track job.

    1. Now, it is possible to monitor the job by choosing the Runs tab.
    2. It may take a few minutes to run the entire job. It took nearly 8 minutes to process approximately 2.50 GB (67,540 compressed files) with 20 DPUs. After the job is processed, you should see your job with the status Succeeded.

    Job runs monitoring dashboard showing successful execution on June 5, 2025, running from 12:28:03 to 12:36:37 with 8 minutes 19 seconds duration.

    Now your data should be saved for a preview visualization demo in a folder named s3://blog-sedona-nessie-<account_number>-<aws_region>/visualization/.

    Performance insights

    The workload characterization of this job reveals a CPU-intensive profile, primarily because of the processing of small binary files with GZIP compression and subsequent JSON parsing. Given the inherent nature of this pipeline, which includes Python UDF serialization and partial single-partition write stages, linear scaling does not yield proportional performance gains. The following table presents an analysis of AWS Glue configurations, evaluating the trade-off between computational capacity, execution duration, and associated costs:

    Duration Capacity (DPUs) Worker type Glue version Estimated Cost*
    10 m 7 s 32 DPUs G.1X 5 $2.34
    11 m 50 s 10 DPUs G.1X 5 $0.88
    19 m 7 s 4 DPUs G.1X 5 $0.59
    8 m 19 s 20 DPUs G.2X 5 $1.32

    *Estimated Cost = DPUs x Duration (hours) x $0.44 per DPU-hour (us-east-1)

    Visualizing and analyzing geospatial data with Kepler.gl

    Kepler.gl is an open-source geospatial analysis tool developed by Uber with code available at Github. Kepler.gl is designed for large-scale data exploration and visualization, offering multiple map layers, including point, arc, heatmap, and 3D hexagon. It supports various file formats like CSV, GeoJSON, and KML. In this use case, we will use Kepler.gl to present interactive visualizations that illustrate flight patterns, routes, and densities across global airspace.

    Downloading the geospatial files

    Before we can view the graph, we will need to download the flight files to our local machine, unzip them, and rename them (to make it easier to identify the files).

    1. Open your OS terminal command line.
    2. Create the folders to download the data processed in the steps before. In this case, we create kepler and kepler_csv.
      	#create kepler folders: first folder is to download the files,
      	#second folder is to organize the files to use in the next step
      	mkdir kepler
      	mkdir kepler_csv
      	
    3. Replace the bracketed variables with your account and directory information, then download all the CSV files.
      	#copy the files from Amazon S3 to local machine
      	aws s3 cp s3://blog-sedona-nessie-<account_number>-<aws_region>/visualization/ /<user_directory>/kepler --recursive
      	
    4. Extract the files, rename them, and move them to another folder.
      	# Extract the files processed by Spark and Sedona
      	gzip -d ./kepler/kepler_h3_density/*.gz
      	gzip -d ./kepler/kepler_track_points_sample/*.gz
      	
      	# Rename the Spark output files to more readable names
      	cd ./kepler/kepler_h3_density/
      	ls
      	mv part-00000-*.csv kepler_h3_density.csv
      	cd ..
      	
      	cd ./kepler/kepler_track_points_sample/
      	ls
      	mv part-00000-*.csv kepler_track_points_sample.csv
      	cd ..
      	
      	# Ensure the output folder exists
      	mkdir -p ../kepler_csv
      	
      	# Copy the renamed CSV files to the folder that will be used as input in kepler.gl
      	cp ./kepler/kepler_h3_density/*.csv ../kepler_csv
      	cp ./kepler/kepler_track_points_sample/*.csv ../kepler_csv
      	
    5. Your kepler_csv folder should look similar to the return of the command below.
      	#list the files in the kepler_csv directory
      	ls -l
      	total 11684
      	-rw-rw-r-- 1 ec2-user ec2-user 8630110 Jun 12 14:47 kepler_h3_density.csv
      	-rw-rw-r-- 1 ec2-user ec2-user 3331763 Jun 12 14:47 kepler_track_points_sample.csv
      	

    Visualizing the data in a graph

    Now that you have saved the data to your local machine, you can analyze the flight data through interactive map graphics. To import the data into the Kepler.gl web visualization tool:

    1. Open the Kepler.gl Demo web application.
    2. Load data into Kepler.gl:
      1. Choose Add Data in the left panel.
      2. Drag and drop both CSV files (flight_points and h3_density) into the upload area.
      3. Confirm that both datasets are loaded successfully.
    3. Delete all layers.
    4. Create the Flight Density Layer:
      1. Choose Add Layer in the left panel.
      2. In Basic, choose H3 as the layer type, then add the following configuration:
        1. Layer Name: Flight Density
        2. Data Source: kepler_h3_density.csv
        3. Hex ID: h3_index
      3. In the Fill Color section:
        1. Color: point_count
        2. Color Scale: Quantile.
        3. Color Range: Choose a blue/green gradient.
      4. Set Opacity to 0.7.
      5. In the Coverage section, set it to 0.9.
    5. Create the Flight Tracks Layer:
      1. Choose Add Layer in the left panel.
      2. In Basic, choose Point as the layer type, then add the following configuration:
        1. Layer Name: Flight Tracks
        2. Data Source: kepler_track_points_sample.csv
        3. Columns:
          1. Latitude: lat
          2. Longitude: lon
      3. In the Fill Color section:
        1. Solid Color: Orange
        2. Opacity: 0.3
      4. Set the Point’s Radius to 1
    6. The layers should look similar to the following figure.

    Kepler.gl layer configuration panel for Flight Density H3 layer using kepler_h3_density.csv data source.

    1. The graph visualization should now show flight density through color-coded hexagons, with individual flight tracks visible as orange points:

    Kepler.gl interactive map visualization displaying global flight density heatmap. High-density areas shown in yellow over North America, particularly the United States.

    There you go! Now that you have knowledge about geospatial data and have created your first use case, take the opportunity to do some analysis and learn some interesting facts about flight patterns.

    It is possible to experiment with other interesting types of analysis in Kepler.gl, such as Time Playback.

    Clean up

    To clean up your resources, complete the following tasks:

    1. Delete the AWS Glue job process_sedona_geo_track.
    2. Delete content from the Amazon S3 buckets: blog-sedona-artifacts-<account_number>-<aws_region> and blog-sedona-nessie-<account_number>-<aws_region>.

    Conclusion

    In this post, we showed how processing geospatial data can present significant challenges due to its complex nature (from big data to data structure format). For this use case of flight trackers, it involves vast amounts of information across multiple dimensions such as time, location, altitude, and flight paths, however, the combination of Spark’s distributed computing capabilities and Sedona’s optimized geospatial functions helps overcome those challenges. The spatial partitioning and indexing features of Sedona, coupled with Spark’s framework, enable us to perform complex spatial joins and proximity analyses efficiently, simplifying the overall data processing workflow.

    The serverless nature of AWS Glue eliminates the need for managing infrastructure while automatically scaling resources based on workload demands, making it an ideal platform for processing growing volumes of flight data. As the volume of flight data grows or as processing requirements fluctuate, with AWS Glue, you can quickly adjust resources to meet demand, ensuring optimal performance without the need for cluster management.

    By converting the processed results into CSV format and visualizing them in Kepler.gl, it is possible to create interactive visualizations that reveal patterns in flight paths, and you can efficiently analyze air traffic patterns, routes, and other insights. This end-to-end solution demonstrates how a modern data strategy in AWS with the support of open-source tools can transform raw geospatial data into actionable insights.


    About the authors

    Ruan

    Ruan Roloff is a Lead GTM Specialist Architect for Analytics and AI at AWS. During his time at AWS, he was responsible for the data journey and AI product strategy of customers across a range of industries, including finance, oil and gas, manufacturing, digital natives, public sector, and startups. He has helped these organizations achieve multi-million dollar use cases. Outside of work, Ruan likes to assemble and disassemble things, fish on the beach with friends, play SFII, and go hiking in the woods with his family.

    Lucas

    Lucas Vitoreti is a ProServe Data & Analytics Specialist at AWS with 12+ years in the data domain. Architects and delivers solutions for data warehouses, lakes, lakehouses, and meshes, helping organizations transform their data strategies and achieve business outcomes. Expertise in scalable data architectures and guiding data-driven transformations. He balances professional life with weightlifting, music, and family time.

    Denys

    Denys Gonzaga is a ProServe Consultant at AWS, he is an experienced professional with over 15 years of working across multiple technical domains, with a strong focus on development and data analytics. Throughout his career, he has successfully applied his skills in various industries, including aerospace, finance, telecommunications, and retail. Outside of AWS, Denys enjoys spending time with his family and playing video games.

    Building unified data pipelines with Apache Iceberg and Apache Flink

    Post Syndicated from Nikhil Jha original https://aws.amazon.com/blogs/big-data/building-unified-data-pipelines-with-apache-iceberg-and-apache-flink/

    You can process real-time data from your data lake with Amazon Managed Service for Apache Flink without maintaining two separate pipelines. Yet many teams do exactly that, and the cost adds up fast. In this post, you build a unified pipeline using Apache Iceberg and Amazon Managed Service for Apache Flink that replaces the dual-pipeline approach. This walkthrough is for intermediate AWS users who are comfortable with Amazon Simple Storage Service (Amazon S3) and AWS Glue Data Catalog but new to streaming from Apache Iceberg tables.

    The dual-pipeline problem

    Traditional dual-pipeline architecture with separate batch and streaming paths, each with its own ingestion, processing, storage, and serving layers, processing the same source data independently.

    This dual-pipeline approach creates three problems:

    • Double the infrastructure costs. You run and pay for two separate compute environments, two storage layers, and two sets of monitoring. For example, if you’re spending $10,000/month on separate streaming and batch infrastructure, a meaningful portion of that spend is pure duplication.
    • Data synchronization issues. Your batch and streaming consumers read from different copies of the data, processed at different times. When a transaction shows up in your real-time dashboard but not in your batch report (or vice versa), debugging the inconsistency takes hours.
    • Operational complexity. Two pipelines mean two deployment processes, two failure modes to monitor, and two sets of schema evolution to manage. Your team spends time reconciling systems instead of building features.

    Where this pattern fits

    Before diving into the implementation, consider whether streaming from your data lake is the right approach for your use case.

    Streaming from Apache Iceberg tables works well when you need data available within seconds to minutes and you query recent data frequently, multiple times per hour. Common scenarios include:

    • Operational data stores — Stream customer profile updates to serve downstream applications like recommendation engines. When a customer updates their preferences, those changes reach your operational data store within seconds.
    • Fraud detection — Stream transactions for immediate analysis. Start with a 3-second monitor interval and adjust based on your detection accuracy needs.
    • Live dashboards — Power real-time analytics directly from your lake. This is the strongest starting point if you’re evaluating the approach for the first time, because the feedback loop is immediate and straightforward to validate.
    • Event-driven architectures — Trigger downstream processes based on data changes in your Apache Iceberg tables.

    Batch processing remains more cost-effective when you process data once per day or less, or you primarily query historical data. Batch queries on Apache Iceberg tables cost less because they don’t require a continuous Apache Flink runtime.

    How Apache Iceberg solves this

    Apache Iceberg’s snapshot-based architecture removes the need for a separate streaming pipeline. Think of snapshots like Git commits for your data. Each time you write data to your Iceberg table, Iceberg creates a new snapshot that points to the new data files while preserving references to existing files. Apache Flink reads only the changes between snapshots (the new files that arrived after the last checkpoint), rather than scanning the entire table. Atomicity, Consistency, Isolation, Durability (ACID) transactions prevent your concurrent reads and writes from producing partial or inconsistent results. For example, if your batch extract, transform, and load (ETL) job is writing 10,000 records while your Flink application is reading, ACID transactions mean that your streaming query sees either the complete batch of 10,000 records or none of them, not a partial set that could skew your analytics.

    The result is a single pipeline that handles both real-time and batch access from the same data, through the same storage layer, with the same schema.

    Solution architecture

    Your architecture uses four AWS services and one open source table format working together. The following diagram shows how these components connect, replacing the dual-pipeline pattern shown earlier with a single unified flow.

    Unified pipeline architecture with data flowing from Amazon S3 through Apache Iceberg tables, with AWS Glue Data Catalog managing metadata, and Amazon Managed Service for Apache Flink consuming incremental snapshots for near real-time processing.

    Your source data lands in Amazon S3 as Apache Iceberg table files. AWS Glue Data Catalog tracks the metadata and schema. When new data arrives, Apache Iceberg creates a new snapshot that your application detects. Your Flink application monitors these snapshots and processes new records incrementally, reading only the files that arrived after the last checkpoint, not the entire table.

    You use four main components:

    • Amazon S3 — Foundational storage layer for your data lake
    • Data Catalog — Metadata and schema management for Apache Iceberg tables
    • Apache Iceberg — Table format with snapshot-based streaming capabilities
    • Amazon Managed Service for Apache Flink — Stream processing and incremental consumption

    Important notices

    Before implementing this solution, evaluate these risks for your environment:

    • Data security: Streaming from data lakes exposes data to additional processing systems. Classify your data before implementation—customer profile updates and transaction data typically contain personally identifiable information (PII) and treat them as confidential. Apply encryption at rest and in transit for confidential data. Key risks include unauthorized data access through misconfigured Amazon S3 bucket policies or overly permissive IAM roles. Mitigations: use the resource-scoped IAM policy and TLS-enforcing bucket policy provided in the Security section.
    • Data integrity: Misconfigured checkpoints or schema changes during streaming can lead to data inconsistency. Mitigations: enable exactly-once processing semantics and test schema evolution in a non-production environment first.
    • Compliance: Verify that real-time data processing meets your regulatory requirements. For workloads subject to HIPAA, confirm that you use HIPAA Eligible Services and have a Business Associate Agreement (BAA) with AWS. For PCI-DSS or GDPR workloads, review the relevant compliance documentation on the AWS Compliance page. Implement data retention policies that comply with your regulatory framework.
    • Cost: Nearly continuous streaming incurs ongoing compute costs. Monitor usage to avoid unexpected charges. Cost estimates in this post are based on pricing as of March 2026 and might change. Verify current pricing on the relevant AWS service pricing pages.
    • Operational: Pipeline failures might impact downstream systems. Implement monitoring and alerting before running in production.

    Prerequisites

    Before you begin, make sure that you have the following in place. This walkthrough assumes intermediate Python skills (comfortable with functions, error handling, and environment variables), basic Apache Flink concepts (streaming compared to batch processing), and basic AWS Identity and Access Management (AWS IAM) knowledge (creating roles and attaching policies). Plan for approximately 90–120 minutes, including setup, implementation, and testing. First-time setup might take longer as you download dependencies and configure AWS resources. Expected AWS costs: approximately $5–10 if you complete the walkthrough within 2 hours and clean up resources immediately afterward. The primary cost driver is Amazon Managed Service for Apache Flink runtime ($0.11/hour per Kinesis Processing Unit (KPU)). You can minimize costs by stopping your application when not in use.

    • An AWS account with AWS IAM permissions for: s3:GetObject, s3:PutObject, s3:ListBucket on your data bucket; glue:GetDatabase, glue:GetTable for catalog access; and flink:CreateApplication, flink:StartApplication for Amazon Managed Service for Apache Flink
    • An existing Amazon S3 bucket for your data lake
    • An AWS Glue Data Catalog database configured
    • Apache Flink 1.19.1 installed locally
    • Python 3.8 or later
    • Java 11 or a more recent version
    • AWS Command Line Interface (AWS CLI) configured with credentials (aws configure)

    Required Java Archive (JAR) dependencies

    You need multiple JAR files because your Flink application coordinates between different systems—Amazon S3 for storage, AWS Glue for metadata, Hadoop for file operations, and Apache Iceberg for the table format. Each JAR handles a specific part of this integration. Missing even one causes ClassNotFoundException errors at runtime.

    • iceberg-flink-runtime-1.19-1.6.1.jar — Core Apache Iceberg integration with Apache Flink
    • iceberg-aws-bundle-1.6.1.jar — AWS-specific Apache Iceberg functionality for Amazon S3 and AWS Glue
    • flink-s3-fs-hadoop-1.19.1.jar — Provides Apache Flink read and write access to Amazon S3
    • flink-sql-connector-hive-3.1.3_2.12-1.19.1.jar — Hive metastore connector for catalog compatibility
    • hadoop-common-3.4.0.jar — Core Hadoop libraries required by Apache Iceberg
    • flink-shaded-hadoop-2-uber-2.8.3-10.0.jar — Repackaged Hadoop dependencies that avoid version conflicts with Apache Flink
    • hadoop-hdfs-client-3.4.0.jar — Hadoop Distributed File System (HDFS) client libraries for file system operations
    • flink-json-1.19.1.jar — JSON format support for Apache Flink
    • hadoop-aws-3.4.0.jar — Hadoop integration with AWS services
    • hadoop-client-3.4.0.jar — Hadoop client libraries
    • aws-java-sdk-bundle-1.12.261.jar — AWS SDK for authentication and service access
    jars = [
        "flink-s3-fs-hadoop-1.19.1.jar",
        "flink-sql-connector-hive-3.1.3_2.12-1.19.1.jar",
        "hadoop-common-3.4.0.jar",
        "flink-shaded-hadoop-2-uber-2.8.3-10.0.jar",
        "iceberg-flink-runtime-1.19-1.6.1.jar",
        "iceberg-aws-bundle-1.6.1.jar",
        "hadoop-hdfs-client-3.4.0.jar",
        "flink-json-1.19.1.jar",
        "hadoop-aws-3.4.0.jar",
        "hadoop-client-3.4.0.jar",
        "aws-java-sdk-bundle-1.12.261.jar"
    ]

    Technical implementation

    The sample code in this post is available under the MIT-0 license.This section walks you through building the streaming pipeline step by step. You create a single Python file, iceberg_streaming.py, with three functions that run in sequence. Your main() function calls them in order: set up the Apache Flink environment, register the Data Catalog, then start the streaming query.

    Set up your Apache Flink environment

    To prepare your Apache Flink environment:

    1. Download the required JAR files listed in the prerequisites section.
    2. Place the JAR files in a lib directory in your project folder.
    3. Configure your HADOOP_CLASSPATH environment variable to point to the lib directory.
    4. Create your streaming execution environment by adding the following function to iceberg_streaming.py:
    def setup_environment():
        """Configure the Flink streaming runtime."""
        try:
            os.environ['HADOOP_CLASSPATH'] = os.path.join(os.getcwd(), 'lib', '*')
            env = StreamExecutionEnvironment.get_execution_environment()
            env.set_parallelism(1)
            settings = EnvironmentSettings.new_instance().in_streaming_mode().build()
            t_env = StreamTableEnvironment.create(env, settings)
            return t_env
        except Exception as e:
            print(f"Failed to initialize Flink environment: {e}")
            raise
    1. Verify your environment by running flink –version. If the command isn’t found, confirm that Apache Flink 1.19.1 is installed and that your PATH includes the Flink bin directory.

    Configure AWS Glue Data Catalog

    To connect your Flink application to Data Catalog:

    1. Open your iceberg_streaming.py file.
    2. Add the create_iceberg_source() function shown in the following section.
    3. Replace the placeholder values with your actual AWS resources before running. These values are static configuration strings, not user input — do not construct them from external or untrusted sources at runtime.
    4. Save the file.
    def create_iceberg_source(t_env):
        """Register the AWS Glue Data Catalog as an Iceberg catalog."""
        try:
            catalog_sql = """
            CREATE CATALOG glue_catalog WITH (
                'type'='iceberg',
                'catalog-impl'='org.apache.iceberg.aws.glue.GlueCatalog',
                'warehouse'='s3://<example-data-lake-bucket>',
                'io-impl'='org.apache.iceberg.aws.s3.S3FileIO',
                'aws.region'='us-east-1',
                'hadoop-conf.fs.s3a.aws.credentials.provider'=
                    'com.amazonaws.auth.DefaultAWSCredentialsProviderChain',
                'hadoop-conf.fs.s3a.endpoint'='s3.amazonaws.com',
                'property-version'='1'
            )
            """
            t_env.execute_sql(catalog_sql)
            t_env.use_catalog("glue_catalog")
            t_env.use_database("streaming_db")
        except Exception as e:
            print(f"Failed to configure Iceberg catalog: {e}")
            raise

    Set up streaming logic

    This function configures Apache Flink to monitor your Apache Iceberg table continuously and process new records as they arrive. Checkpointing runs every 10 seconds to track progress—if the job restarts, it resumes from the last checkpoint rather than reprocessing the entire table.Notice the monitor-interval parameter, it controls how frequently Apache Flink checks for new Apache Iceberg snapshots. A 3-second interval provides near real-time processing but generates approximately 1,200 Amazon S3 LIST API calls per hour (at $0.005 per 1,000 requests, roughly $0.04/month per table based on pricing as of March 2026). For less time-sensitive workloads, increase this to 30s to reduce API costs by 90%.Replace customer_events with the name of your Apache Iceberg table in Data Catalog:

    def process_record(row):
        """Validate and process each record from the stream."""
        try:
            if row is None:
                raise ValueError("Received null row")
            required_fields = ["event_type", "timestamp"]
            for field in required_fields:
                if field not in row:
                    raise ValueError(f"Missing required field: {field}")
            # Validate field types and content
            if not isinstance(row.get("event_type"), str) or len(row["event_type"]) > 256:
                raise ValueError("event_type must be a string under 256 characters")
            if not isinstance(row.get("timestamp"), (str, int)):
                raise ValueError("timestamp must be a string or integer")
            # Replace with your business logic
            print(f"Processing record: {row}")
        except ValueError as e:
            print(f"Validation error for record {row}: {e}")
        except Exception as e:
            print(f"Error processing record {row}: {e}")
    def stream_data(t_env):
        """Start the streaming query and process results."""
        try:
            configuration = t_env.get_config().get_configuration()
            configuration.set_string("table.dynamic-table-options.enabled", "true")
            configuration.set_string("execution.checkpointing.interval", "10000")
            query = """
            SELECT * FROM customer_events /*+ OPTIONS(
                'streaming'='true',
                'monitor-interval'='3s',
                'table.exec.iceberg.cell-based-snapshot'='true'
            ) */
            """
            table_result = t_env.execute_sql(query)
            with table_result.collect() as results:
                for row in results:
                    process_record(row)
        except Exception as e:
            print(f"Streaming query failed: {e}")
            raise

    Putting it together

    Your main() function calls the three steps in order:

    def main():
        try:
            t_env = setup_environment()
            create_iceberg_source(t_env)
            stream_data(t_env)
        except Exception as e:
            print(f"Pipeline failed: {e}")
            raise
    if __name__ == "__main__":
        main()

    Run the pipeline locally:python iceberg_streaming.pyPackage the application and submit it to Amazon Managed Service for Apache Flink using the console or the AWS Command Line Interface (AWS CLI).

    Running in production

    Moving from a local test to a production deployment requires tuning four areas: performance, monitoring, cost, and security. This section covers the key decisions for each.

    Performance tuning

    Determine your latency requirements before tuning. For fraud detection, you need subsecond processing. For daily reporting dashboards, you can tolerate minutes of delay.

    Partition pruning reduces the amount of data scanned per query. Proper partitioning can significantly reduce query times for time series data partitioned by date. To implement, create your Apache Iceberg table with partition columns (PARTITIONED BY (date_column) in your CREATE TABLE statement), then include partition filters in your WHERE clause: WHERE date_column >= CURRENT_DATE - INTERVAL '7' DAY.

    Parallel processing matches your data volume and throughput requirements. For most workloads under 10,000 records per second, a parallelism of 1–4 is sufficient. Scale up incrementally and monitor backpressure metrics (indicators that data arrives faster than your pipeline processes it, causing queuing) to find the right setting.

    Checkpoint tuning balances reliability and latency. Consider how much data you can afford to reprocess after a failure. If you process 1,000 records per second with 10-second checkpoints, a failure means reprocessing up to 10,000 records. When that’s acceptable, 10 seconds works well. For faster recovery or higher volumes, reduce to 5 seconds.

    Resource allocation — Right-size your Apache Flink cluster to avoid over-provisioning. Monitor CPU and memory utilization during your initial runs and adjust task manager resources accordingly.

    Monitoring

    Configure your production deployment with the following checkpoint settings. These work well for moderate data volumes (up to 10,000 records per second), providing exactly-once processing semantics. This means that the pipeline processes each record exactly once, even if your application restarts. Adjust the checkpoint interval based on your latency requirements. Add this to your setup_environment() function after creating the table environment.

    config_dict = {
        "execution.checkpointing.interval": "30000",
        "execution.checkpointing.mode": "EXACTLY_ONCE",
        "execution.checkpointing.timeout": "600000",
        "state.backend": "filesystem",
        "state.checkpoints.dir": "s3://<example-data-lake-bucket>/checkpoints"
    }

    Use Amazon CloudWatch to track checkpoint duration, records processed per second, and backpressure metrics. A 10-second checkpoint interval means writing state to Amazon S3 360 times per hour. For a 1 MB state size, that’s approximately 8.6 GB per day in checkpoint storage—at Amazon S3 Standard pricing of $0.023/GB, roughly $0.20/day or $6/month per application based on current pricing. If the checkpoint duration exceeds 50% of your interval, increase the interval or add parallelism.

    Cost management

    Use Amazon S3 Intelligent-Tiering for your Apache Iceberg data files, which typically have predictable access patterns after initial processing. Configure Apache Iceberg’s table expiration to automatically clean up early snapshots. This can reduce storage costs by an estimated 20–30%, though your results vary depending on write frequency and retention policies.

    Right-size your Apache Flink resources based on actual throughput needs. Start with a minimal configuration and scale up based on observed backpressure and checkpoint duration metrics. Use Amazon Elastic Compute Cloud (Amazon EC2) Spot Instances where workload interruptions are acceptable, for example, in development and testing environments.

    Set data retention policies on both your Apache Iceberg tables and checkpoint storage to avoid storing data longer than necessary.

    Security

    Security is a shared responsibility between you and AWS. AWS is responsible for the security of the cloud, including the hardware, software, networking, and facilities that run AWS services. You are responsible for security in the cloud, configuring access controls, encrypting data, and managing your application security. Apply these controls in priority order.

    AWS IAM roles — Use AWS IAM roles with least-privilege access, scoped to specific resources. The following example policy restricts permissions to your data lake bucket and AWS Glue catalog:

    {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Effect": "Allow",
          "Action": ["s3:GetObject", "s3:PutObject"],
          "Resource": "arn:aws:s3:::<example-data-lake-bucket>/*"
        },
        {
          "Effect": "Allow",
          "Action": "s3:ListBucket",
          "Resource": "arn:aws:s3:::<example-data-lake-bucket>",
          "Condition": {
            "StringEquals": {
              "aws:SourceVpce": "<your-vpc-endpoint-id>"
            }
          }
        },
        {
          "Effect": "Allow",
          "Action": ["glue:GetDatabase", "glue:GetTable"],
          "Resource": [
            "arn:aws:glue:us-east-1:<account-id>:catalog",
            "arn:aws:glue:us-east-1:<account-id>:database/streaming_db",
            "arn:aws:glue:us-east-1:<account-id>:table/streaming_db/*"
          ]
        },
        {
          "Effect": "Allow",
          "Action": ["kms:Decrypt", "kms:GenerateDataKey"],
          "Resource": "arn:aws:kms:us-east-1:<account-id>:key/<your-kms-key-id>"
        }
      ]
    }

    Scoping permissions to specific Amazon S3 buckets, AWS Glue databases, and AWS Key Management Service (AWS KMS) keys restrict access to only the resources your pipeline requires. Review IAM policies quarterly using the IAM Access Analyzer to identify and remove unused permissions.

    Encryption — Configure server-side encryption with AWS Key Management Service (AWS KMS) customer managed keys (SSE-KMS) for your Amazon S3 buckets. Using customer managed keys requires additional review from your security team. Confirm your key management policies, rotation procedures, and access controls before implementation. Enable automatic key rotation annually. For encryption in transit, enforce TLS by adding a bucket policy that denies non-HTTPS access:

    {
      "Effect": "Deny",
      "Principal": "*",
      "Action": ["s3:GetObject", "s3:PutObject", "s3:ListBucket"],
      "Resource": [
        "arn:aws:s3:::<example-data-lake-bucket>/*",
        "arn:aws:s3:::<example-data-lake-bucket>"
      ],
      "Condition": {
        "Bool": { "aws:SecureTransport": "false" }
      }
    }

    Amazon S3 bucket hardening — Enable Block Public Access on your buckets to prevent accidental public exposure:

    aws s3api put-public-access-block \
      --bucket <example-data-lake-bucket> \
      --public-access-block-configuration \
      BlockPublicAcls=true,IgnorePublicAcls=true,BlockPublicPolicy=true,RestrictPublicBuckets=true

    Enable versioning on buckets that store critical data and checkpoints to protect against accidental deletion. For production environments with sensitive data, consider enabling MFA Delete on versioned buckets. Enable S3 server access logging to track requests for security auditing.

    Amazon Virtual Private Cloud (Amazon VPC) –Use Amazon VPC endpoints for private communication between your Apache Flink cluster and AWS services, removing public internet routing by keeping traffic within the AWS network.

    Access logging – Enable AWS CloudTrail data events to log Amazon S3 object-level API calls (GetObject, PutObject) and Data Catalog API calls. Store logs in a separate Amazon S3 bucket with restricted access and enable log file integrity validation. Run regular compliance checks using AWS Config.

    Operational practices

    Set up a continuous integration and continuous deployment (CI/CD) pipeline to automate deployment and testing. Use version control to track schema and code changes. With Apache Iceberg’s schema evolution support, you can add columns without rewriting existing data files. Establish rollback procedures using Apache Iceberg’s snapshot-based architecture, so you can roll back to a previous table state if a bad write corrupts your data.

    Troubleshooting

    If you run into issues during setup or execution, use the following table to diagnose common errors.

    Error Cause Solution
    ClassNotFoundException Missing JAR files Check the dependencies in your lib directory and confirm HADOOP_CLASSPATH points to the correct path
    Table not found Database name mismatch Check that the database name in t_env.use_database() matches the AWS Glue database where you registered your table
    Checkpoint failures Amazon S3 permissions Check that your Amazon S3 bucket policy grants s3:PutObject for the checkpoint location
    AWS credential errors Missing AWS IAM configuration Check that the AWS IAM role attached to your Apache Flink application has glue:GetTable, glue:GetDatabase, and s3:GetObject permissions on the relevant resources
    Snapshot not found Table modified during query Increase monitor-interval or implement retry logic in your process_record() function
    Schema mismatch Table schema changed between snapshots Review Apache Iceberg schema evolution settings and confirm backward compatibility

    Clean up

    To avoid ongoing charges, delete the resources that you created during this walkthrough.

    1. Stop your Amazon Managed Service for Apache Flink application. Open the Amazon Managed Service for Apache Flink console, choose your application name, choose Stop, and confirm the action. Or use the AWS CLI:

    aws kinesisanalyticsv2 stop-application --application-name your-app-name

    1. Delete the Amazon S3 buckets that you created for data storage and checkpoints. For instructions, see Deleting a bucket in the Amazon S3 User Guide.
    2. Remove the Apache Iceberg tables from your Data Catalog.
    3. Delete the AWS IAM roles and policies created specifically for this walkthrough.
    4. If you created an Amazon VPC or Amazon VPC endpoints for testing, delete those resources.

    Conclusion

    Maintaining separate streaming and batch pipelines doubles your infrastructure costs, creates data synchronization issues, and adds operational complexity that slows your team down. In this post, you replaced that dual-pipeline architecture with a single system built on Apache Iceberg and Amazon Managed Service for Apache Flink. You configured a Flink environment with the required JAR dependencies, connected it to Data Catalog, and implemented streaming queries that read new records incrementally with exactly-once processing semantics. The same data, the same storage layer, the same schema—accessible to both your real-time and batch consumers.

    To extend this solution, try these next steps based on your use case:

    • If you’re processing high volumes (>10,000 records/sec): Start with partition pruning. Add PARTITIONED BY (date_column) to your table definition, this typically reduces query times by 60–80%.
    • If you need production monitoring: Implement custom Amazon CloudWatch metrics. Track checkpoint duration, records processed per second, and backpressure to catch issues before they impact your pipeline.
    • If you have variable workloads: Configure auto scaling for your Apache Flink cluster. See the Amazon Managed Service for Apache Flink Developer Guide for detailed guidance.

    Share your implementation experience in the comments, your use case, data volumes, latency improvements, and cost reductions help other readers calibrate their expectations. To get started, try the Amazon Managed Service for Apache Flink Developer Guide and the Apache Iceberg documentation on the Apache Iceberg website.


    About the authors

    Headshot of Nikhil

    Nikhil Jha

    Nikhil Jha is a Principal Delivery Consultant at AWS Professional Services, helping enterprises navigate complex modernization journeys. He builds data and AI solutions for AWS customers. Outside of work he likes swimming and hiking.

    Headshot of Vyas

    Vyas Garigipati

    Vyas Garigipati is a Delivery Consultant at AWS Professional Services, with experience building scalable, distributed systems. He specializes in designing and building AI-powered, high-availability, multi-region architectures and helps customers deploy resilient, production ready solutions on AWS.

    Headshot of Vafa

    Vafa Ahmadiyeh

    Vafa Ahmadiyeh is a Principal Lead Technologist at AWS, specializing in cloud architecture for the global financial services sector. He partners with major financial institutions to modernize their infrastructure and accelerate their migration to AWS, with a focus on building secure, scalable distributed systems and platforms designed for highly regulated environments.

    Headshot of Kaushal

    Kaushal (KK) Agrawal

    Kaushal (KK) Agrawal is a Principal Technology Delivery Leader for the Digital Native Segment of AWS Professional Services, working with top-tier customers to deliver innovation at the intersection of AI and Cloud.

    How to clone an AWS CloudHSM cluster across Regions

    Post Syndicated from Desiree Brunner original https://aws.amazon.com/blogs/security/how-to-clone-an-aws-cloudhsm-cluster-across-regions-2/

    Important: As of January 1, 2025, Client SDK 3 tools (CMU and KMU) are no longer supported. This guide has been updated to use Client SDK 5 commands exclusively. Ensure you’re using the latest Client SDK 5 version (5.17 or later) for the most recent features and security improvements.

    You can use AWS CloudHSM to generate, store, import, export, and manage your cryptographic keys. It also permits hash functions to compute message digests and hash-based message authentication codes (HMACs) and supports cryptographically signing data and verifying signatures. To help ensure redundancy of data and simplification of the disaster recovery process, AWS recommends you to clone your CloudHSM cluster into a different AWS Region. By doing this, you can synchronize keys, including non-exportable keys, across Regions. Non-exportable keys can only be synchronized to cloned clusters. Non-exportable keys are keys that can never leave the CloudHSM device in plaintext. They reside on the CloudHSM device and are encrypted for security purposes.

    In this post, I show you how to set up one cluster in Region 1 and how to use the CopyBackupToRegion feature to clone the cluster and hardware security modules (HSMs) to a virtual private cloud (VPC) in Region 2.

    Note: This post doesn’t include instructions on how to set up a cross-Region VPC to synchronize HSMs across the two cloned clusters. If you need to set up a cross-Region VPC, see Building a Scalable and Secure Multi-VPC AWS Network Infrastructure.

    Solution overview

    You clone a cluster to another Region in a two-step process:

    1. Copy a backup to the destination Region
    2. Create a new cluster from this backup

    To complete this solution, you can use either the AWS Command Line Interface (AWS CLI) or the CloudHSM API. For this post, I show you how to use the AWS CLI to copy the cluster backup from Region 1 to Region 2 and then launch a new cluster from that copied backup.
    Figure 1 illustrates the process described in this post.

    Figure 1: Architecture diagram

    Figure 1: Architecture diagram

    Here’s how the process works:

    1. CloudHSM creates a backup of the cluster and stores it in an Amazon Simple Storage Service (Amazon S3) bucket owned by the CloudHSM service.
    2. You use the AWS CLI API command to copy the backup to another Region.
    3. When the backup is completed, you use that backup to then create a new cluster and HSMs.
    Note: Backups can’t be copied across partitions like the AWS GovCloud Regions, China Region and AWS European Sovereign Cloud.

    As with all cluster backups, when you copy the backup to a new Region, it’s stored in an S3 bucket owned by a CloudHSM account. CloudHSM manages the security and storage of cluster backups for you. This means the backup in both Regions will also have the durability of Amazon S3, which has 99.999999999% durability. The backup in Region 2 will be encrypted and secured in the same way as your backup in Region 1. You can read more about the encryption process of your CloudHSM backups in AWS CloudHSM cluster backups.
    Any HSMs created in this cloned cluster will have the same users and keys as the original cluster at the time the backup was taken. From this point on, you must manually keep the cloned clusters in sync. Specifically:

    • If you create users after creating your new cluster from the backup, you must create them on both clusters manually.
    • If you change the password for a user in one cluster, you must change the password on the cloned clusters to match.
    • If you create more keys in one cluster, you must sync them to at least one HSM in the cloned cluster. After you sync the key from cluster 1 to cluster 2, the CloudHSM automated cluster synchronization will take care of syncing the keys in the second cluster.

    Prerequisites

    Before starting, ensure you have the following in place:

    Note: Syncing keys across clusters in more than one Region will only work if all clusters are created from the same backup. This is because synchronization requires the same secret key—called a masking key—to be present on the source and destination HSM. The masking key is specific to each cluster. It can’t be exported, and can’t be used for any purpose other than synchronizing keys across HSMs in a cluster.

    Step 1: Create your first cluster in Region 1

    The first step in cloning your CloudHSM cluster is to create the initial cluster—which will serve as the foundation for your cross-Region deployment—in your source Region.

    Create the cluster

    Replace <SUBNET_ID_1> with one of your private subnets. Make a note of the cluster ID to use later:
    aws cloudhsmv2 create-cluster --hsm-type hsm2m.medium --subnet-ids <SUBNET_ID_1>

    Launch the EC2 client

    Launch an Amazon Elastic Compute Cloud (Amazon EC2) instance in your public subnet. See Step 1 of Get started with Amazon EC2 for detailed steps.

    Create the first HSM

    Replace <CLUSTER_ID> with the ID you recorded earlier and <AVAILABILITY_ZONE> with the Availability Zone matching your private subnet (for example, us-east-1a):
    aws cloudhsmv2 create-hsm --cluster-id <CLUSTER_ID> --availability-zone <AVAILABILITY_ZONE>

    Initialize the cluster

    Before you initialize the cluster, create a self-signed certificate and use it to sign the cluster’s certificate signing request (CSR). Once you have the signed certificate, initialize the cluster:

    aws cloudhsmv2 initialize-cluster \
        --cluster-id <CLUSTER_ID> \
        --signed-cert file://<CLUSTER_ID>_CustomerHsmCertificate.crt \
        --trust-anchor file://customerCA.crt
    

    Important: Copy the certificate used to sign your cluster’s CSR to to maintain a secure connection.

    After the command completes, the cluster transitions to the Initialized state. Copy the certificate used to sign your cluster’s CSR to /opt/cloudhsm/etc so that the CloudHSM client can verify the cluster’s identity when you configure it in the next step:

    sudo cp _CustomerHsmCertificate.crt /opt/cloudhsm/etc/
    sudo cp customerCA.crt /opt/cloudhsm/etc/

    Install the CloudHSM Client SDK 5

    Download and install the latest CloudHSM Client SDK 5 (version 5.17 or later):
    For example, for Amazon Linux 2023:

    wget https://s3.amazonaws.com/cloudhsmv2-software/CloudHsmClient/Amzn2023/cloudhsm-cli-latest.amzn2023.x86_64.rpm
    sudo yum install -y ./cloudhsm-cli-latest.amzn2023.x86_64.rpm

    Configure the client

    Configure the CloudHSM client with your HSM’s elastic network interface (ENI IP) address:
    configure-cli -a <HSM_IP>

    Activate the cluster

    To activate the cluster, run the CloudHSM CLI in interactive mode.

    cloudhsm-cli interactive

    You can run user list to see the admin user, which is not yet activated.

    aws-cloudhsm > user list
    {
      "error_code": 0,
      "data": {
        "users": [
          {
            "username": "admin",
            "role": "unactivated-admin",
            "locked": "false",
            "mfa": [],
            "cluster-coverage": "full"
          },
          {
            "username": "app_user",
            "role": "internal(APPLIANCE_USER)",
            "locked": "false",
            "mfa": [],
            "cluster-coverage": "full"
          }
        ]
      }
    }
    

    Use the cluster activate command to set the initial admin password.

    aws-cloudhsm > cluster activate
    Enter password:<NewPassword>
    Confirm password:<NewPassword>
    {
      "error_code": 0,
      "data": "Cluster activation successful"
    }
    

    When completed, sign out using the command quit, then sign back in with the new password, using the command login --username admin --role admin.

    After doing this, you can create the first crypto user (CU). You create the user by running the command: user create --username <USERNAME> --role crypto-user. For more information, see HSM user types for CloudHSM CLI. Crypto users are permitted to create and share keys on the CloudHSM.

    When completed, sign out using the command quit.

    Step 2: Create keys in Region 1

    Create a non-exportable AES-256 key:

    aws-cloudhsm > key generate-symmetric aes \
        --label aes-example \
        --key-length-bytes 32 \
        --attributes extractable=false
    

    Make note of the key reference returned in the output, because you’ll need it for synchronization later.

    Step 3: Trigger a backup of your cluster

    To trigger a backup for Region 2:

    1. Add another HSM to your cluster in Region 1 (can be done using the AWS Management Console or AWS CLI)
    2. The backup will contain:
      • All users (crypto officers (COs), crypto users (CUs), and appliance users)
      • All key material on the HSMs
      • All configurations and policies
    Note: The user portion is critical because keys can only be synced across clusters to the same user.

    Record the backup ID to use later. You can find this in the CloudHSM console under Backups, or using the following command:

    aws cloudhsmv2 describe-backups --cluster-id

    To avoid unnecessary charges, you can delete the additional HSM after the backup is created.

    Step 4: Copy your backup Between Regions

    Before you can transfer the backup to your destination Region, you need to configure the appropriate IAM permissions to allow the copy operation.

    IAM permissions

    Ensure proper permissions are configured for your IAM role or user. You need CloudHSM administrator privileges. Here’s an example permissions policy:

    {
       "Version": "2012-10-17",
       "Statement": {
          "Effect": "Allow",
          "Action": [
             "cloudhsm:*",
             "ec2:CreateNetworkInterface",
             "ec2:DescribeNetworkInterfaces",
             "ec2:DescribeNetworkInterfaceAttribute",
             "ec2:DetachNetworkInterface",
             "ec2:DeleteNetworkInterface",
             "ec2:CreateSecurityGroup",
             "ec2:AuthorizeSecurityGroupIngress",
             "ec2:AuthorizeSecurityGroupEgress",
             "ec2:RevokeSecurityGroupEgress",
             "ec2:DescribeSecurityGroups",
             "ec2:DeleteSecurityGroup",
             "ec2:CreateTags",
             "ec2:DescribeVpcs",
             "ec2:DescribeSubnets",
             "iam:CreateServiceLinkedRole"
          ],
          "Resource": "*"
       }
    }
    

    Copy the backup

    To copy your backup from Region 1 to Region 2, you need:

    • The destination Region
    • The source cluster ID and backup ID (you can use either or both) found in the CloudHSM console

    If you specify only the cluster ID, the most recent backup will be chosen. For a specific backup, use the backup ID.

    aws cloudhsmv2 copy-backup-to-region \
        --destination-region <DESTINATION_REGION> \
        --backup-id <BACKUP_ID>
    

    Example response:

    {
        "DestinationBackup": {
            "SourceBackup": "backup-4kuraxsqetz",
            "SourceCluster": "cluster-kzlczlspnho",
            "CreateTimestamp": 1531742400,
            "SourceRegion": "us-east-1"
        }
    }
    

    After copying, you will see a new backup ID in your console. Use this to create your new cluster in Region 2:

    aws cloudhsmv2 create-cluster \
        --hsm-type hsm2m.medium \
        --subnet-ids <SUBNET_ID_REGION_2> \
        --source-backup-id <BACKUP_ID_REGION_2> \
    

    Certificate transfer

    Copy the cluster certificate from the original cluster to the new Region:

    1. Open two terminal sessions (one for each HSM)
    2. Copy the certificate content from cluster 1
    3. Create and paste into a new file in cluster 2

    The certificate is required for encrypted connections between your client and HSM instances.

    Security group configuration

    Add the cloned cluster’s Security Group to your EC2 client instance:

    1. Select the Security Group for your EC2 client in the EC2 console
    2. Choose “Add rules”
    3. Add a rule allowing traffic from the cluster’s Security Group ID on port 2225

    Then retrieve the ENI IP address of the HSM in Region 2 using the following command, and make a note of the output—you will use it in the next step to configure cross-Region connectivity:

    aws cloudhsmv2 describe-clusters \
        --filters clusterIds=<cluster_ID_region_2> \
        --region <region_2> \
        --query 'Clusters.Hsms.EniIp' \
        --output text
    

    Step 5: Configure cross-Region connectivity

    To enable the CloudHSM CLI to communicate with both clusters simultaneously, add the Region 2 cluster to your existing client configuration using the ENI IP address you retrieved in the previous step:

    Step 6: Synchronize keys between clusters

    To synchronize keys between your source and destination clusters, you first need to verify which users and keys exist before replicating them.

    configure-cli add-cluster \
        --cluster-id <cluster_ID_region_2> \
        --endpoint <hsm_eni_ip_region_2> \
        --region <region_2>

    The CloudHSM CLI will now communicate with both clusters simultaneously using the certificates already configured during the initial setup, enabling key synchronization using the masking key shared between cloned clusters.

    List users and keys

    First, verify users and list available keys:
    # List all users
    cloudhsm-cli user list

    # List keys for specific user
    cloudhsm-cli key list --username

    Replicate keys

    To replicate a key from Region 1 to Region 2:

    cloudhsm-cli key replicate \
        --filter key-reference=<key_ref> \
        --source-cluster-id <source_cluster_ID> \
        --destination-cluster-id <destination_cluster_ID>

    Verify the key replication by listing keys again:

    cloudhsm-cli key list --username <username>

    The output should show identical key references on both clusters. Repeat this process for any additional keys that you want to synchronize.

    Points to remember

    After cloning a cluster to a backup cluster, remember these important points:

    • Always manually update users across clusters after the initial backup
    • Use key replication for any keys created after the initial backup
    • Keep your Client SDK 5 tools updated for the latest features and security improvements
    • The January 1, 2025, end-of-support date for Client SDK 3 tools (CMU and KMU) means you should migrate to Client SDK 5 as soon as possible

    Client SDK 5 supports ARM64 architecture on the following Linux distributions:

    • Amazon Linux 2023
    • Amazon Linux 2
    • Red Hat Enterprise Linux (RHEL) 8 (8.3+)
    • Red Hat Enterprise Linux (RHEL) 9 (9.2+)
    • Red Hat Enterprise Linux (RHEL) 10 (10.0+)
    • Ubuntu 22.04 LTS
    • Ubuntu 24.04 LTS
    • Debian 12
    • USE Linux Enterprise Server 15

    Conclusion

    You now have a fault-tolerant AWS CloudHSM environment with synchronized keys across Regions using the latest tools and best practices. By implementing this cross-Region cluster configuration, you gain improved disaster recovery capabilities, reduced risk of data loss, and enhanced business continuity for your cryptographic operations. This approach helps ensure that your critical cryptographic keys remain available even in the event of a Regional outage, providing the resilience that enterprise workloads demand.

    If you have feedback about this post, submit comments in the Comments section below. For questions about this post, start a new thread on the AWS re:Post.

    Desiree Brunner

    Desiree Brunner

    Desiree is a Security Specialist Solutions Architect working with regulated customers as part of the AWS EMEA Security & Compliance team. She builds on her background in DevOps and platform engineering to support her customers in designing secure, compliant cloud environments. Passionate about mental health and knowledge sharing, she regularly speaks at AWS events and supports teams on their cloud security journey.

    Rickard Löfström

    Rickard Löfström

    Rickard guides enterprises in building secure cloud environments as a Specialist Solutions Architect in the AWS EMEA Security & Compliance team. He advises customers on implementing AWS security services, focusing on identity management, data protection, and infrastructure security controls. He enjoys translating complex security requirements into technical solutions that enable organizations to meet their security objectives while maintaining operational efficiency.

    Securely connecting on-premises data systems to Amazon Redshift with IAM Roles Anywhere

    Post Syndicated from Zainab Syeda original https://aws.amazon.com/blogs/big-data/securely-connecting-on-premises-data-systems-to-amazon-redshift-with-iam-roles-anywhere/

    Securely connecting on-premises data systems to Amazon Redshift requires removing static credentials while preserving seamless access for your data teams. This solution extends connectivity from your on-premises data centers to Amazon Redshift by using short-lived, auditable credentials. All traffic remains within trusted, private channels.

    Developers and data engineers need a process to run ingestion pipelines, Extract, Transform, Load (ETL) jobs, and analytics queries without managing static credentials or complex authentication flows. You can use AWS Identity and Access Management (IAM) Roles Anywhere to obtain temporary security credentials in IAM. This service extends the short-term credential model of AWS beyond the cloud and allows on-premises workloads to authenticate with IAM using X.509 certificates from an existing certificate authority. This approach removes static IAM access keys and applies least-privilege access through IAM policies. Every request is recorded in AWS CloudTrail. Paired with private Domain Name System (DNS) and Amazon Virtual Private Cloud (Amazon VPC) endpoints for Amazon Redshift, it keeps authentication and data flows inside private networks without traversing the public internet.

    In this post, you will learn how to use AWS IAM Roles Anywhere with Amazon Redshift for secure, private connections. This removes the need to expose traffic to the public internet or manage long-lived access keys.

    The challenge

    Organizations connecting on-premises data systems to Amazon Redshift typically choose from several established security patterns, each with tradeoffs in risk, complexity, and operational overhead. Static IAM access keys are straightforward to adopt but require ongoing rotation, secure distribution, and storage across systems. Their long-lived nature increases the impact of accidental exposure in code, configuration files, or logs. Shared database or service credentials can streamline setup but often reduce auditability, weaken least-privilege controls, and create accountability challenges across teams. VPN or private network connections improve network isolation, yet they still require strong application-layer authentication and add infrastructure management burdens. Custom secret-management or credential-brokering solutions can reduce reliance on long-lived credentials, but they introduce additional components that must be built, integrated, and maintained. As organizations scale, these patterns often force tradeoffs between strong security controls and the developer productivity needed to build and operate data pipelines efficiently.

    Solution overview

    The solution integrates on-premises workloads with Amazon Redshift using IAM Roles Anywhere and the built-in IAM authentication of Amazon Redshift. The core idea is that on-premises workloads use X.509 certificates to obtain short-term IAM credentials, then exchange them for temporary Amazon Redshift database credentials. Both provisioned clusters and serverless workgroups are supported. The architecture consists of these main components:

    • Amazon Redshift Service Endpoint – Handles secure API calls such as GetClusterCredentials, GetCredentials, and GetClusterCredentialsWithIAM. The on-premises workload uses these API endpoints to request temporary database credentials.
    • Amazon Redshift Cluster Endpoint – Provides the connection point for database operations on provisioned Amazon Redshift clusters. After obtaining temporary credentials, applications and tools like JDBC/ODBC drivers or psql connect to the cluster endpoint. They use this connection to execute SQL queries, load data, and perform analytics tasks.
    • Amazon Redshift Serverless Workgroup Endpoint – Serves the same function as the cluster endpoint but for serverless deployments. After temporary credentials are retrieved through the GetCredentials API, applications connect to this endpoint using standard database drivers (JDBC/ODBC) or command line tools like psql to run queries and load data.
    • Certificate authority – For this post, we use AWS Private Certificate Authority (AWS Private CA) as the certificate authority (CA) source. Alternatively, you can integrate with an external CA. For more details, see IAM Roles Anywhere with an external certificate authority.
    • X.509 Certificate – We use a sample private certificate stored in AWS Certificate Manager (ACM) and issued by AWS Private CA.
    • IAM Roles Anywhere – Issues short-term AWS credentials to on-premises processes based on X.509 certificates from an organization’s certificate authority. These temporary credentials allow the workload to assume an IAM role that grants access to Amazon Redshift APIs.

    To retrieve temporary credentials using IAM Role Anywhere, we use the credential_process parameter in AWS Command Line Interface (AWS CLI) profile configurations to trigger an external process that generates or retrieves credentials. This post uses X.509 certificates to authenticate and return temporary IAM credentials through IAM Roles Anywhere. The AWS IAM Roles Anywhere Credential Helper is executed to handle the signing process for the CreateSession API, returning credentials in a JSON format that applications and tools can consume.

    Amazon Redshift provides several APIs that work together to support temporary, IAM-based authentication for different deployment scenarios. When connecting to a provisioned Amazon Redshift cluster, applications typically use the GetClusterCredentials API, which returns short-term database credentials tied to an IAM role’s permissions. For organizations with fully IAM-managed identities, GetClusterCredentialsWithIAM streamlines this process by automatically mapping the IAM identity to a database user, removing the need to specify usernames manually. In serverless deployments, the GetCredentials API performs the same function, issuing temporary credentials for Amazon Redshift Serverless workgroups based on IAM permissions. Collectively, these APIs keep static credentials from being stored or distributed while offering flexible integration paths for both provisioned and serverless Amazon Redshift architectures.

    Flow overview

    An on-premises ETL job begins by initiating a request and authenticates with AWS using IAM Roles Anywhere to assume an IAM role securely. After obtaining temporary security credentials, the workload calls the Amazon Redshift service endpoint to execute the GetClusterCredentials API, which returns short-term database credentials. These credentials allow the workload to connect to the Amazon Redshift cluster endpoint through a VPC endpoint. This enables running SQL queries or loading data into the cluster as part of the ETL process.

    Prerequisites

    You must have the following prerequisites to follow along with this post.

    AWS account requirements

    • An AWS account with permissions to deploy AWS CloudFormation templates.
    • Access to AWS CloudShell for exporting a sample private certificate that we create using AWS CloudFormation in a later step.

    Remote environment

    Network Connectivity requirements

    Deploy AWS resources with AWS CloudFormation

    1. Navigate to the AWS CloudFormation console.
    2. Choose Create Stack.
    3. Download the redshift-iamra-template template.
    4. For Specify template, choose Upload a template file and upload redshift-iamra-template.
    5. Choose Next.
    6. Enter a unique name for Stack name. The default value is redshift-test.
    7. Configure the stack parameters. The following table provides default values.
    Parameter name Default value Description
    VPCCIDR 10.0.0.0/16 CIDR block for the VPC
    PrivateSubnet1CIDR 10.0.1.0/24 CIDR block for the first private subnet
    PrivateSubnet2CIDR 10.0.2.0/24 CIDR block for the second private subnet
    CACommonName redshift-ca.example.com Common Name for the Certificate
    CAOrganization Example Corp Organization for the Certificate Authority
    CACountry US Country for the Certificate Authority
    CAValidityInDays 1826 Validity period in days for the CA Certificate (5 years)
    RedshiftClusterIdentifier my-redshift-cluster Identifier for the Amazon Redshift cluster
    RedshiftDatabaseName dev Name of the initial database in the Amazon Redshift cluster
    RedshiftMasterUsername admin Main username for the Amazon Redshift cluster
    RedshiftNodeType ra3.xlplus Node type for the Amazon Redshift cluster
    ServerlessNamespace my-serverless-namespace Namespace identifier for Amazon Redshift Serverless
    ServerlessWorkgroup my-serverless-workgroup Workgroup identifier for Amazon Redshift Serverless
    1. Select the acknowledgement checkbox and choose Create Stack. Stack deployment takes about 10 minutes to complete.
    1. When stack creation is complete, navigate to the Outputs tab on the AWS CloudFormation console and note down the values for the resources that the stack created.

    The following table shows a summarized view of the output values.

    Output Description Example value
    CertificateAuthorityArn Amazon Resource Name (ARN) of the Private Certificate Authority arn:aws:acm-pca:aa-example-1:111122223333:certificate-authority/a1b2c3d4-5678-90ab-cdef-EXAMPLE22222
    ClientCertificateArn ARN of the sample client certificate arn:aws:acm:aa-example-1:111122223333:certificate/a1b2c3d4-5678-90ab-cdef-EXAMPLE11111
    ProfileArn ARN of the IAM Roles Anywhere profile arn:aws:rolesanywhere:aa-example-1:111122223333:profile/a1b2c3d4-5678-90ab-cdef-EXAMPLE44444
    RedshiftAccessRoleArn ARN of the Amazon Redshift Access role arn:aws:iam::1222345677:role/Redshift-test-RedshiftAccessRole
    TrustAnchorArn ARN of the IAM Roles Anywhere profile. You will use this value for configuring credential_process for IAM Roles Anywhere in a later step. arn:aws:rolesanywhere:aa-example-1:111122223333:trust-anchor/a1b2c3d4-5678-90ab-cdef-EXAMPLE33333
    RedshiftClusterEndpoint Private endpoint of the Amazon Redshift Cluster my-redshift-cluster-123456789012.aa-example-1.redshift.amazonaws.com
    RedshiftClusterPort Port of the Amazon Redshift Cluster 5439
    ServerlessWorkgroupEndpoint Private endpoint of Amazon Redshift Serverless Workgroup my-serverless-workgroup-123456789012.aa-example-1.redshift.serverless.amazonaws.com

    Export a sample private certificate using CloudShell

    To export a sample private certificate using CloudShell, complete the following steps.

    1. Open CloudShell. For more details, see Navigating the AWS CloudShell interface.
    2. Export the certificate ARN from the CloudFormation outputs. If you changed the stack name in the previous step, use that value for <stack-name>. Otherwise, use the default value redshift-public-iam-roles-anywhere.
    export CERT_ARN=$(aws cloudformation describe-stacks \
        --stack-name <stack-name> \
        --query 'Stacks[0].Outputs[?OutputKey==`ClientCertificateArn`].OutputValue' \
        --output text)
    
    1. Extract the certificate and private key files:
    # Generate and save the passphrase
    export PASSPHRASE=$(openssl rand -base64 32)
    # Export certificate using environment variables
    aws acm export-certificate \
        --certificate-arn $CERT_ARN \
        --passphrase $(echo -n "$PASSPHRASE" | base64) \
        > cert_export.json
    # Extract components to separate files
    jq -r '.Certificate' cert_export.json > certificate.pem
    jq -r '.PrivateKey' cert_export.json > encrypted_private_key.pem
    # Decrypt the private key
    openssl rsa -in encrypted_private_key.pem -out private_key.pem -passin pass:"$PASSPHRASE"
    # Clear environment variables
    unset PASSPHRASE CERT_ARN
    1. Download the extracted certificate and private key files from CloudShell:
    /home/cloudshell-user/certificate.pem
    /home/cloudshell-user/private_key.pem
    1. Secure the private key on your local workstation.

    After downloading the files, restrict file permissions to prevent unauthorized access:

    chmod 400 private_key.pem chmod 400 certificate.pem

    For production workloads, consider storing private keys in your operating system’s keychain (macOS Keychain, Windows Certificate Store), a hardware security module (HSM), or a secrets management tool rather than as files on disk.

    Configure an AWS CLI profile
    These are the steps to configure an AWS CLI profile on your system:
    1. Store the downloaded certificate and private key to your environment. For an automated approach to generate and rotate certificates, see Set up AWS Private Certificate Authority to issue certificates for use with IAM Roles Anywhere.
    2. Create a new profile named onprem-redshift. This invokes the credential process. Replace the placeholders with your specific values. Find the values for trusted-anchor-arn, profile-arn, and role-arn in your CloudFormation stack outputs.
    aws configure set profile.onprem-redshift.credential_process "</path/to/aws_signing_helper> credential-process \
          --certificate </path/to/certificate.pem> \
          --private-key </path/to/private_key.pem> \
          --trust-anchor-arn <trusted-anchor-arn> \
          --profile-arn <profile-arn> \
          --role-arn < role-arn>"
    1. Verify your configuration. Open the ~/.aws/config file and confirm that it contains a profile.
    [profile onprem-redshift]
    credential_process = </path/to/aws_signing_helper> credential-process       
    --certificate </path/to/certificate.pem>       
    --private-key </path/to/private_key.pem>       
    --trust-anchor-arn <trusted-anchor-arn>       
    --profile-arn <profile-arn>       
    --role-arn <role-arn>

    Test the solution

    Follow these steps to validate your setup for provisioned clusters to confirm end-to-end connectivity:

    1. Verify network connectivity

    Before testing authentication, confirm that your on-premises environment can reach the Amazon Redshift cluster endpoint:

    telnet my-redshift-cluster.abc123.us-east-1.redshift.amazonaws.com 5439

    If the connection succeeds, you should see a response indicating the port is open. If it fails, verify your VPN/Direct Connect configuration and security group rules.

    1. Create database user

    If you haven’t already created a user, connect to your Amazon Redshift as the main user and create a dedicated user for testing:

    CREATE USER analytics_user PASSWORD '[PASSWORD]';

    1. Retrieve Amazon Redshift database credentials

    With the configuration in place, request temporary database credentials from Amazon Redshift:

    aws redshift get-cluster-credentials \
      --db-user analytics_user \
      --cluster-identifier my-redshift-cluster \
      --region us-east-1 \
      --profile onprem-redshift
    This call returns a short-lived username and password that’s valid for connecting to the cluster. By default, the temporary credentials expire in 900 seconds. You can optionally specify a duration between 900–3600 seconds (15–60 minutes).

    1. Connect using JDBC/ODBC or psql

    Use the issued credentials in your connection string. For JDBC:

    jdbc:redshift://my-redshift-cluster.abc123.redshift.amazonaws.com:5439/dev?ssl=true&UID=analytics_user&PWD=<temporary_password>

    For psql:

    PGPASSWORD=<temporary_password> psql \
      -h my-redshift-cluster.abc123.redshift.amazonaws.com \
      -p 5439 \
      -U analytics_user \
      -d dev \
      --set=sslmode=verify-full

    Validate and monitor

    • Test authentication flows end-to-end using your ETL jobs.
    • Review AWS CloudTrail logs to validate. It records role assumptions and Amazon Redshift API calls.
    • Monitor session expiration to help workloads handle credential refresh seamlessly.

    Testing end-to-end connectivity for Amazon Redshift Serverless

    The testing process for Amazon Redshift Serverless follows a similar pattern to provisioned clusters, with minor differences in the API calls and connection parameters. These steps validate connectivity to your serverless workgroup.

    1. Verify network connectivity

    telnet my-serverless-workgroup.abc123.us-east-1.redshift.amazonaws.com 5439

    1. Retrieve Amazon Redshift Serverless database credentials
    aws redshift-serverless get-credentials \
      --workgroup-name my-serverless-workgroup \
      --db-name dev \
      --region us-east-1 \
      --profile onprem-redshift
    1. Connect using JDBC/ODBC or psql
    PGPASSWORD="<password_from_get_credentials>" psql \
      -h my-serverless-workgroup.abc12.us-east-1.redshift-serverless.amazonaws.com \
      -p 5439 \
      -U "IAMR:Redshift-IAMRA-RedshiftAccessRole" \
      -d dev \
      --set=sslmode=verify-full

    Clean up

    To avoid future charges, remove the deployed resources:

    1. Delete the CloudFormation stack.
    2. Remove the generated files from CloudShell:

    rm cert_export.json encrypted_private_key.pem certificate.pem private_key.pem

    Conclusion

    In this post, we showed how to implement IAM Roles Anywhere with Amazon Redshift so that enterprises can securely connect on-premises data systems to their cloud data warehouse without relying on static credentials or public internet access. This architecture provides short-lived, auditable credentials, integrates with existing certificate authorities, and helps ensure authentication and data flows remain private and trusted.
    With this approach, data engineers and developers can run ingestion pipelines, ETL jobs, and analytics queries, while security teams maintain full control through IAM governance and CloudTrail auditing. You can remove manual credential rotation tasks, allow your data engineers to connect to Amazon Redshift without managing static keys, and achieve complete audit trails through CloudTrail integration for your hybrid analytics environments.

    To get started, deploy the solution using the CloudFormation template and follow the steps in this post. To learn more about the services used, see the following resources:


    About the authors

    Kanwar Bajwa is a Principal Enterprise Account Engineer at AWS who works with customers to optimize their use of AWS services and achieve their business objectives.

    Xiaoxue Xu is a Solutions Architect for AWS based in Toronto. She primarily works with Financial Services customers to help secure their workload and design scalable solutions on the AWS Cloud.

    Zainab Syeda is a Technical Account Manager at Amazon Web Services in Toronto. She works with customers in the Financial Services segment, helping them leverage cloud-native solutions at scale.

    Getting started with Apache Iceberg write support in Amazon Redshift – Part 2

    Post Syndicated from Sanket Hase original https://aws.amazon.com/blogs/big-data/getting-started-with-apache-iceberg-write-support-in-amazon-redshift-part-2/

    In Getting started with Apache Iceberg write support in Amazon Redshift – part 1, you learned how to create Apache Iceberg tables and write data directly from Amazon Redshift to your data lake. You set up external schemas, created tables in both Amazon Simple Storage Service (Amazon S3) and S3 Tables, and performed INSERT operations while maintaining ACID (Atomicity, Consistency, Isolation, Durability) compliance.

    Amazon Redshift now supports DELETE, UPDATE, and MERGE operations for Apache Iceberg tables stored in Amazon S3 and Amazon S3 table buckets. With these operations, you can modify data at the row level, implement upsert patterns, and manage the data lifecycle while maintaining transactional consistency using familiar SQL syntax. You can run complex transformations in Amazon Redshift and write results to Apache Iceberg tables that other analytics engines like Amazon EMR or Amazon Athena can immediately query.

    In this post, you work with customer and orders datasets that were created and used in the previously mentioned post to demonstrate these capabilities in a data synchronization scenario.

    Solution overview

    This solution demonstrates DELETE, UPDATE, and MERGE operations for Apache Iceberg tables in Amazon Redshift using a common data synchronization pattern: maintaining customer records and orders data across staging and production tables. The workflow includes three key operations:

    • DELETE – Remove customer records based on opt-out requests
    • UPDATE – Modify existing customer information
    • MERGE – Synchronize order data between staging and production tables using upsert patterns
    Figure : solution overview

    Figure 1: solution overview

    The solution uses a staging table (orders_stg) stored in an S3 table bucket for incoming data and reference tables (customer_opt_out) in Amazon Redshift for managing data lifecycle operations. With this architecture, you can process changes efficiently while maintaining ACID compliance across both storage types.

    Prerequisites

    For this walkthrough, you should have completed the setup steps from Getting started with Apache Iceberg write support in Amazon Redshift – part 1, including:

    • Create an Amazon Redshift data warehouse (provisioned or Serverless)
    • Set up the required IAM role (RedshifticebergRole) with appropriate permissions
    • Create an Amazon S3 bucket and S3 Table bucket
    • Configure AWS Glue Data Catalog database and setting up access
    • Set up AWS Lake Formation permissions
    • Create the customer Apache Iceberg table in Amazon S3 standard buckets with sample customer data
    • Create the orders Apache Iceberg table in Amazon S3 Table buckets with sample order data
    • Amazon Redshift data warehouse on p200 version or higher

    Data preparation

    In this section, you set up the sample data needed to demonstrate MERGE, UPDATE, and DELETE operations. To prepare your data, complete the following steps:

    1. Log in to Amazon Redshift using Query Editor V2 with the Federated user option.
    2. Create the orders_stg and customer_opt_out tables with sample data:
    CREATE TABLE "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders_stg
    (
    customer_id BIGINT,
    order_id BIGINT,
    Total_order_amt DECIMAL(10,2),
    Total_order_tax_amt REAL,
    tax_pct DOUBLE PRECISION,
    order_date DATE,
    order_created_at_tz TIMESTAMPTZ,
    is_active_ind BOOLEAN
    )
    USING ICEBERG;
    INSERT INTO "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders_stg
    (order_date, order_id, customer_id, total_order_amt, total_order_tax_amt, tax_pct, order_created_at_tz, is_active_ind)
    VALUES
    ('2024-11-11', 1016, 10, 167.45, 13.40, 0.08, '2024-11-11 06:55:00-06:00', true),
    ('2024-11-12', 1017, 15, 34.99, 2.80, 0.08, '2024-11-12 23:30:30-06:00', true),
    ('2024-11-09', 1014, 9, 500.60, 56.80, 0.09, '2024-11-09 16:20:55-06:00', true),
    ('2024-11-10', 1015, 5, 329.85, 33.51, 0.08, '2024-11-10 11:45:30-06:00', true);
    select * from "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders_stg;
    Figure 2: orders_stg result set

    Figure 2: orders_stg result set

    CREATE TABLE dev.public.customer_opt_out
    (
    customer_id bigint,
    customer_name varchar,
    opt_out_ind char(1),
    cust_rec_upd_ind char(1)
    );
    INSERT INTO dev.public.customer_opt_out VALUES
    (9, 'Customer9 Martinez', 'Y', 'N'),
    (12, 'Customer12 Thomas', 'Y', 'N'),
    (13, 'Customer13 Albon', 'N', 'Y'),
    (14, 'Customer14 Oscar', 'N', 'Y');
    select * from dev.public.customer_opt_out;
    Figure 3: customer_opt_out result set

    Figure 3: customer_opt_out result set

    You can now use the orders_stg and customer_opt_out tables to demonstrate data manipulation operations on the orders and customer tables created in the prerequisite section.

    MERGE

    MERGE conditionally inserts, updates, or deletes rows in a target table based on the results of a join with a source table. You can use MERGE to synchronize two tables by inserting, updating, or deleting rows in one table based on differences found in the other table.

    To perform a MERGE operation:

    1. Verify that the current data in the orders table for order IDs 1014, 1015, 1016, and 1017.You loaded this sample data in Part 1:
    select * from "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders
    where order_id in (1014,1015,1016,1017);
    Figure 4: orders data for existing orders for orders in orders_stg

    Figure 4: orders data for existing orders for orders in orders_stg

    The orders table contains existing rows for order IDs 1014 and 1015.

    1. Run the following MERGE operation using order_id as the key column to match rows between the orders and orders_stg tables:
    MERGE INTO "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders
    USING "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders_stg
    ON orders.order_id = orders_stg.order_id
    WHEN MATCHED THEN UPDATE 
    SET
    customer_id         = orders_stg.customer_id,
    total_order_amt     = orders_stg.total_order_amt,
    total_order_tax_amt = orders_stg.total_order_tax_amt,
    tax_pct             = orders_stg.tax_pct,
    order_date          = orders_stg.order_date,
    order_created_at_tz = orders_stg.order_created_at_tz,
    is_active_ind       = orders_stg.is_active_ind
    WHEN NOT MATCHED THEN INSERT
    VALUES 
    (orders_stg.customer_id,orders_stg.order_id,orders_stg.total_order_amt,orders_stg.total_order_tax_amt,orders_stg.tax_pct,orders_stg.order_date,orders_stg.order_created_at_tz,orders_stg.is_active_ind);

    The operation updates existing rows (1014 and 1015) and inserts new rows for order IDs that don’t exist in the orders table (1016 and 1017).

    1. Verify the updated data in the orders table:
    select * from "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orderswhere order_id in (1014,1015,1016,1017);
    Figure 5: merged data on orders from orders_stg

    Figure 5: merged data on orders from orders_stg

    The MERGE operation performs the following changes:

    • Updates existing rows – Order IDs 1014 and 1015 have updated total_order_amt and total_order_tax_amt values from the orders_stg table
    • Inserts new rows – Order IDs 1016 and 1017 are inserted because they don’t exist in the orders table

    This demonstrates the upsert pattern, where MERGE conditionally updates or inserts rows based on the matching key column.

    UPDATE

    UPDATE modifies existing rows in a table based on specified conditions or values from another table.

    Update the customer Apache Iceberg table using data from the customer_opt_out Amazon Redshift native table. The UPDATE operation uses the cust_rec_upd_ind column as a filter, updating only rows where the value is ‘Y’.

    To perform an UPDATE operation:

    1. Verify the current customer_name values for customer IDs 13 and 14 in customer_opt_out and customer (loaded this sample data in Part 1) tables:
    select * from dev.public.customer_opt_out
    where cust_rec_upd_ind = 'Y';
    Figure 6: verify existing customer data for customers from customer_opt_out

    Figure 6: verify existing customer data for customers from customer_opt_out

    select customer_id,customer_name from dev.demo_iceberg.customer
    where customer_id in(13,14);
    Figure 7: verify existing customer name for customers from customer_opt_out

    Figure 7: verify existing customer name for customers from customer_opt_out

    1. Run the following UPDATE operation to modify customer names based on the cust_rec_upd_ind from customer_opt_out:
    UPDATE dev.demo_iceberg.customerSET customer_name = customer_opt_out.customer_name
    FROM dev.public.customer_opt_out
    WHERE customer_opt_out.cust_rec_upd_ind = 'Y'and customer.customer_id = customer_opt_out.customer_id;
    1. Verify the changes for customer IDs 13 and 14:
    select customer_id,customer_name from dev.demo_iceberg.customer where customer_id in(13,14) order by 1;
    Figure 8: updated customer names in customer table

    Figure 8: updated customer names in customer table

    The UPDATE operation modifies the customer_name values based on the join condition with the customer_opt_out table. Customer IDs 13 and 14 now have updated names (Customer13 Albon and Customer14 Oscar).

    DELETE

    DELETE removes rows from a table based on specified conditions. Without a WHERE clause, DELETE removes all the rows from table.

    Delete rows from the customer Apache Iceberg table using data from the customer_opt_out Amazon Redshift native table. The DELETE operation uses the opt_out_ind column as a filter, removing only rows where the value is ‘Y’.

    To perform a DELETE operation:

    1. Verify the opt-out indicator data in the customer_opt_out table:
    select * from dev.public.customer_opt_out
    where opt_out_ind = 'Y';
    Figure 9: verify customer records for opt out

    Figure 9: verify customer records for opt out

    1. Verify the current customer data for customer IDs 9 and 12:
    select * from dev.demo_iceberg.customerwhere customer_id in(9,12);
    Figure 0: verify existing customers data in customer table for opt out

    Figure 10: verify existing customers data in customer table for opt out

    1. Review the query execution plan:
    EXPLAINDELETE FROM demo_iceberg.customerUSING public.customer_opt_out
    WHERE customer.customer_id = customer_opt_out.customer_id
    AND customer_opt_out.opt_out_ind = 'Y';
    Figure 1: query plan for the DELETE queryThe execution plan shows Amazon S3 scans for Apache Iceberg format tables, indicating that Amazon Redshift removes rows directly from the Amazon S3 bucket.

    Figure 11: query plan for the DELETE query. The execution plan shows Amazon S3 scans for Apache Iceberg format tables, indicating that Amazon Redshift removes rows directly from the Amazon S3 bucket.

    1. Run the following DELETE operation:
    DELETE FROM demo_iceberg.customer
    USING public.customer_opt_out
    WHERE customer.customer_id = customer_opt_out.customer_id
    AND customer_opt_out.opt_out_ind = 'Y';
    1. Verify that the rows were removed:
    select * from dev.demo_iceberg.customer where customer_id in(9,12);
    Figure 2: result set from customer table for opt out customer after delete

    Figure 12: result set from customer table for opt out customer after delete

    The query returns no rows, confirming that customer IDs 9 and 12 were successfully deleted from the customer table.

    Best practices

    After performing multiple UPDATE or DELETE operations, consider running table maintenance to optimize read performance:

    • For AWS Glue tables – Use AWS Glue table optimizers. For more information, see Table optimizers in the AWS Glue Developer Guide.
    • For S3 Tables – Use S3 Tables maintenance operations. For more information, see S3 Tables maintenance in the Amazon S3 User Guide.

    Table maintenance merges and compacts deletion files generated by Merge-on-Read operations, improving query performance for subsequent reads.

    Conclusion

    You can use Amazon Redshift support for DELETE, UPDATE, and MERGE operations on Apache Iceberg tables to build data architectures that combine warehouse performance with data lake scalability. You can modify data at the row level while maintaining ACID compliance, giving you the same flexibility with Apache Iceberg tables as you have with native Amazon Redshift tables.

    Get started:


    About the authors

    Sanket Hase

    Sanket Hase

    Sanket is an Engineering Manager with the Amazon Redshift team, leading query execution teams in the areas of data lake analytics, hardware-software co-design, and vectorized query execution.

    Raghu Kuppala

    Raghu Kuppala

    Raghu is an Analytics Specialist Solutions Architect experienced working in the databases, data warehousing, and analytics space. Outside of work, he enjoys trying different cuisines and spending time with his family and friends.

    Ritesh Sinha

    Ritesh is an Analytics Specialist Solutions Architect based out of San Francisco. He has helped customers build scalable data warehousing and big data solutions for over 16 years. He loves to design and build efficient end-to-end solutions on AWS. In his spare time, he loves reading, walking, and doing yoga.

    Sundeep Kumar

    Sundeep Kumar

    Sundeep is a Sr. Specialist Solutions Architect at Amazon Web Services (AWS), helping customers build data lake and analytics platforms and solutions. When not building and designing data lakes, Sundeep enjoys listening to music and playing guitar.

    Upgrade business messaging with RCS on AWS

    Post Syndicated from Brett Ezell original https://aws.amazon.com/blogs/messaging-and-targeting/upgrade-business-messaging-with-rcs-on-aws/

    SMS remains a reliable workhorse for business-to-consumer reach, but it isn’t without its hurdles. Messages from unrecognized numbers are frequently ignored or flagged as spam, and the limitations of plain text can’t provide the interactive experiences modern customers expect. Rich Communication Services (RCS) on AWS End User Messaging addresses these challenges as the next generation of mobile messaging.

    Before we get into the technical implementation, it is important to understand what RCS is, why it’s becoming the new standard for business-to-consumer (B2C) communication, and the strategic value it brings to your messaging stack.

    The problem with traditional business messaging

    Traditional SMS has long been confined to a “narrow lane” of one-directional alerts—think one-time passcodes (OTP) and basic shipment updates. Because these messages arrive from generic-looking short codes or long codes, recipients have no native way to verify the sender’s legitimacy. As a result, users often do the rational thing: they ignore the message or treat it with suspicion.

    What is RCS?

    RCS is the next-generation messaging protocol developed by the GSM Association (GSMA) to update traditional Short Message Service (SMS) and Multimedia Messaging Service (MMS). Unlike SMS, which relies on the cellular signaling channel, RCS is entirely IP-based, operating over data connectivity (Wi-Fi or mobile data). This shift allows RCS to bring high-resolution media and interactive capabilities directly to the default messaging application.

    The core innovation is the RCS Agent—your verified sending identity. Instead of a random number, recipients see your brand name, logo, and a verified checkmark. This shift from “unknown sender” to “verified brand” transforms the recipient’s behavior from passive ignore to active engagement. When customers trust the sender, they stop only reading alerts and start completing workflows, asking questions, and engaging with AI-powered agents built on services like Amazon Bedrock.

    The business case for RCS

    We can see the future of RCS by looking at markets where over-the-top (OTT) apps like WhatsApp are dominant. In those regions, businesses use messaging for full-lifecycle order management, customer service, and complex scheduling. In markets without that OTT distribution, businesses have been stuck with one-way SMS notifications.

    RCS levels this playing field. By bringing a branded, verified identity natively to the default messaging app, it opens up a range of interactive use cases previously reserved for dedicated apps or websites.

    Where to start?

    When evaluating RCS for your program, we recommend starting with your highest-volume transactional messages. These are often the easiest to migrate because they follow predictable templates. More importantly, they provide the most immediate ROI by maximizing the visibility of your verified identity across your largest customer touchpoints.

    To illustrate the business impact across industries:

    • Ecommerce: Order confirmations arriving from a verified brand logo eliminate the “Is this legitimate?” hesitation customers have with SMS from generic numbers. Customers click tracking links confidently because they recognize the sender immediately.
    • Healthcare: Appointment reminders with verified provider identity reduce no-shows and eliminate verification calls. Patients respond more quickly to verified communications and handle appointment management through messaging rather than calling the office.
    • Financial services: Fraud alerts with verified bank identity increase response rates and reduce phishing confusion. Customers see their bank’s logo and verified badge and know the alert is legitimate — enabling faster fraud detection and prevention.

    Prerequisites

    Before you begin the registration process, make sure that you have the following prerequisites in place:

    • An active AWS account with billing configured.
    • Access to AWS End User Messaging.
    • AWS Identity and Access Management (IAM) permissions to create and manage RCS agents and origination identities.
    • Existing SMS infrastructure to serve as a fallback.
    • A planned timeline that accounts for carrier approval lead times, which vary by country and carrier.
    • A budget for registration and verification fees.

    Timeline, planning, and costs

    Adopting RCS requires careful planning for both timelines and budgets. Carrier approval timelines vary by country and carrier — approval is not instant. Plan and verify that your processes, such as opt-in consent collection and brand asset preparation, are in place well before your intended launch date.

    Registration and usage fees also differ significantly by market. Currently, AWS End User Messaging supports RCS in the United States and Canada, with additional countries planned for future rollout.

    • United States: This market uses a per-segment (160-character) pricing model similar to SMS. It features a higher initial barrier to entry, including a one-time agent setup fee and an annual brand vetting fee.
    • Canada: Canada utilizes a distinct message-based model (“Basic” vs. “Single” messages) rather than segments. Notably, it currently lacks the one-time setup and annual vetting fees found in the US, though a monthly maintenance fee applies globally to all active agents.

    Also note that RCS is billed only upon successful delivery, whereas SMS is charged at the time of the request. For the latest rates and a breakdown of carrier-specific content violation fees, see AWS End User Messaging pricing.

    Note: You are charged only for successfully delivered messages, not delivery attempts. In the United States, long messages are billed per 160-character segment; however, for the Rest of the World (ROW), messages exceeding 160 characters are billed as a single ‘RCS Single’ message. When automatic fallback occurs, you are typically charged only for the successful SMS delivery. While rare, note that if both the RCS and SMS messages reach the device (dual-delivery), charges for both may apply. For more details, see the RCS billing and pricing model.

    RCS and SMS: Better together

    RCS works alongside SMS to create a reliable messaging solution with automatic SMS fallback. AWS End User Messaging ensures reliable delivery by intelligently handling three common scenarios where RCS may be unavailable, triggering an automatic fallback to SMS:

    • Carrier-specific availability — Your RCS agent may be approved on some carriers but still pending on others, or a carrier may not have deployed RCS infrastructure yet. AWS detects this upfront using carrier lookup data and automatically routes via SMS so that the message is delivered.
    • Device compatibility — Not all devices support RCS, even if the carrier does. This includes older Android models, devices with RCS disabled, or iPhones running versions earlier than iOS 18. AWS detects this compatibility upfront where possible and automatically routes the message via SMS so that it reaches the recipient.
    • Temporary connectivity — A device may support RCS but lack data connectivity at the moment of delivery (for example, traveling through a tunnel or with data roaming turned off). The device still has cellular coverage for SMS. AWS falls back to SMS so that the message is delivered.
    SMS text message from short code 47205 showing a Verizon Call Filter trial activation notice in a dark-themed mobile messaging app, with no sender branding, a generic profile icon, and a "Report Spam" warning at the bottom.

    Figure 1: A typical SMS business message often appears from an unrecognizable short code, making it difficult for customers to verify the sender before clicking a link or replying.

    When RCS delivery falls back to SMS because of a lack of data connectivity or other availability reasons, AWS uses sticky sending. The service prioritizes the origination number that most recently delivered successfully to that destination—maintaining that preference for 24 hours before retrying RCS. This ensures consistent, recognizable delivery across various connectivity and compatibility scenarios.

    Effective phone number management is the foundation for fallback behavior. AWS provides three ways to send messages, each with different fallback behavior:

    • Pool-based sending — AWS selects from identities in a specific pool containing your RCS agent and SMS phone numbers. This is the recommended approach for production deployments. Pools give you precise control over which identities are used while AWS handles automatic routing and fallback.
    • Account-level sending — AWS automatically selects the best identity from your entire account. This is similar to the default behavior in Amazon Simple Notification Service (SNS), where you cannot isolate traffic into specific pools. This approach is ideal for development, testing, or simple deployments where a single identity is used for all messaging use cases within a country.
    • Direct send — You specify an exact RCS agent as the origination identity. The message fails if RCS isn’t available. Use this for testing or when you want to handle fallback yourself.

    For production messaging where delivery is critical, use pool-based or account-level sending for reliable delivery. Pools route your fallback SMS messages through consistent, recognizable numbers your customers trust.

    RCS vs. SMS at a glance

    For a detailed comparison of capabilities, see the following table.

    Feature SMS RCS
    Character limit 160 characters No practical limit
    Media support MMS (compressed) High-resolution images, video, audio
    Read receipts No Yes
    Typing indicators No Yes
    Interactive buttons No Yes
    Branded identity Basic (Sender ID) Full (Verified Profile)
    Delivery over internet No Yes
    Verified RCS business profile for "Go Big or Go Home!" showing a branded hippo logo, purple banner, company tagline, and contact options for call, website, and email in a mobile messaging app.

    Figure 2: The final result – A verified brand profile featuring your high-resolution logo, banner image, and custom brand colors—elements that significantly increase trust and click-through rates compared to standard SMS.

    The recommended adoption path

    Consider a phased approach to RCS adoption that aligns with your operational readiness. First, register your brand and get carrier approval. Next, move your existing SMS use cases to RCS. Finally, after you are comfortable with the channel, test and expand with advanced use cases.

    How to register

    Brand asset requirements

    Before submitting your registration, prepare the following brand assets. Carriers reject assets that don’t meet exact specifications, so verify these requirements before submitting.

    Asset Requirements
    Logo 224×224 pixels, PNG with transparency, under 50 KB
    Banner 1440×448 pixels, PNG or JPEG, under 200 KB
    Brand Color Hex format (e.g. #1A73E8), minimum 4.5:1 contrast ratio

    Note: A 4.5:1 contrast ratio means your brand color must be at least 4.5 times brighter (or darker) than its background. This threshold meets WCAG 2.1 Level AA standards, ensuring your brand name is legible for users with moderate vision loss or color blindness. To verify compliance, use a Contrast Checker to test your hex code against a solid white background.

    Use case selection

    Your use case determines what types of messages you can send in production. Select carefully before submitting — the use case does not affect approval timeline, but it does determine your message restrictions and how carriers perceive your traffic.

    Use Case What you can send
    OTP Authentication codes and security verification only
    Transactional Order updates, shipping notifications, account alerts
    Promotional Marketing campaigns and offers (requires opt-in consent)
    Multi-use Combined transactional and promotional messaging

    Why not just choose Multi-use for everything?

    While Multi-use offers the most flexibility, it is often subject to stricter carrier scrutiny during the vetting process. Carriers prefer single-purpose agents (like OTP) because they provide a more predictable and trustworthy experience for the recipient. If you have a high-volume OTP use case, registering it separately can help protect your sender reputation from being impacted by the lower engagement rates typically associated with promotional marketing.

    Important: Agents must be use-case specific. Sending message types that don’t match your registered use case could result in suspension.

    Registration steps

    To submit your registration, complete the following steps:

    1. Sign in to the AWS Management Console and open the AWS End User Messaging console.
    2. In the navigation pane, under Configurations, choose RCS agents.
    3. Choose Create RCS Agent. This creates an AWS RCS Agent and then immediately guides you through creating a testing registration in a single workflow.
    RCS tester invitation from RBM Tester Management showing interactive "Make me a tester" and "Decline" buttons, user selection, and confirmation message for the "Go Big or Go Home!" RCS agent in a dark-themed mobile messaging app.

    Figure 3: Once your agent is created in the AWS console, your registered test devices will receive an invitation like this one. Tapping ‘Make me a tester’ allows you to immediately see your branded content in action.

    1. The next screen shows an introduction to RCS and explains the setup process. Review the information and choose Next to continue.
    2. On the Agent details page, set the following:
      1. Friendly name — A console-only label for your AWS RCS Agent. This is an internal name for your reference (stored as a tag) and is not the name displayed on recipients’ phones. The friendly name is not available through the API.
      2. Deletion protection — (Optional) Enable to prevent accidental deletion of the agent.
      3. Tags — (Optional) Add tags to organize and identify your agent.
    3. In the Brand information section of the same page, enter the following:
      1. Display name — The brand name that recipients see alongside your RCS messages.
      2. Description — A brief description of your brand or business.
      3. Use case — Select the primary use case for your RCS messaging (for example, transactional notifications, marketing, or customer support).
    4. In the Brand assets section of the same page, upload the following:
      1. Logo — 224 × 224 pixels, PNG with transparency, under 50 KB.
      2. Banner image — 1440 × 448 pixels, PNG or JPEG, under 200 KB.
      3. Brand color — A hex color code (for example, #1A73E8) with a minimum contrast ratio of 4.5:1 against a white background.

    Important: Some brand assets cannot be changed after the agent is submitted for registration. Prepare your final brand assets before creating the agent. If you want to experiment first, you can quickly create a test agent using this flow, then create a fresh AWS RCS Agent with finalized brand assets later.

    1. On the Compliance keywords page, configure your keywords and auto-response messages.
    2. On the Review page, verify all your settings.
    3. Choose Validate and submit to create the AWS RCS Agent and submit the testing registration.

    Testing and production launch phases

    Launching RCS follows a distinct path from testing to production:

    1. Testing Registration: The initial guided console flow creates your AWS RCS Agent and a testing agent, or RBM Agent(RCS Business Messaging Agents). This allows you to validate your integration immediately by sending messages to registered test devices without waiting for carrier approval.
    2. Country Launch Registrations: After testing is complete, you must submit separate country launch registrations for each production market.

    Carrier review and approval

    • Independent Approval: Each country launch registration undergoes a separate review process by every carrier in that target country.
    • Partial Reach: Approval is per-carrier. You are considered “partially approved” as soon as at least one carrier approves your agent, allowing you to start sending production messages to recipients on that carrier’s network via the SendTextMessage API.
    • Timelines: For both the U.S. and Canada, expect the carrier approval process to take several months. To avoid delays, verify that all registration fields are accurate and, for U.S. launches, provide a clear screen recording demonstrating your intended use case.

    Important considerations

    Multi-level identity: Think of the AWS RCS Agent as your brand’s unified identity. Under this one resource, you will have multiple RCS for Business IDs: one for your testing agent and separate IDs for each country launch (e.g., one for the US and one for Canada).

    Carrier approval is per-carrier, not all-at-once: You do not need to wait for every carrier to approve before you begin sending. As soon as an individual carrier approves your agent, you can reach that carrier’s subscribers.

    Sandbox testing: Testing with sandbox agents does not require carrier approval and can begin immediately upon submission. Note that testing messages are charged at standard RCS rates.

    Finality of configurations: Brand assets are defined on each specific registration and are final after submission. While minor updates are permitted through supporting documentation, significant structural changes require creating a new agent. Plan your configuration carefully before you submit.

    Accuracy matters: Filling out registration forms incorrectly can result in lengthy delays or rejection. Double-check all information before submitting and verify that business documents are current and valid. In this early phase of RCS adoption, carriers have been approving recognizable brands more readily.

    Managing costs and usage

    Monitor your RCS message volume through Amazon CloudWatch metrics and set up billing alerts to track spending against your SMS baseline. For more information, see AWS End User Messaging pricing.

    Conclusion

    In this post, we showed you how RCS on AWS End User Messaging solves customer engagement challenges through verified branding, interactive features, and automatic SMS fallback. You get a branded messaging experience with the reliability of SMS built in. Evaluate your current SMS message volume and identify high-priority transactional messages that would benefit from verified branding. Consider migrating these high-impact use cases first to establish your brand presence and improve customer trust.

    Get started today

    Ready to implement RCS? Here are your next steps:

    • If you’re ready to register: Contact your AWS account team or AWS Support to begin the registration process.
    • If you want to learn more: Review the AWS End User Messaging and RCS documentation.
    • If you’re still evaluating: Start by auditing your current SMS message volume and identifying high-priority transactional messages that would benefit from verified branding.

    About the authors

    Implementing Kerberos authentication for Apache Spark jobs on Amazon EMR on EKS to access a Kerberos-enabled Hive Metastore

    Post Syndicated from Krishna Kumar Venkateswaran original https://aws.amazon.com/blogs/big-data/implementing-kerberos-authentication-for-apache-spark-jobs-on-amazon-emr-on-eks-to-access-a-kerberos-enabled-hive-metastore/

    Many organizations run their Apache Spark analytics platforms on Amazon EMR on Amazon Elastic Compute Cloud (Amazon EC2), using Kerberos authentication to secure connectivity between Spark jobs and a centralized shared Apache Hive Metastore (HMS). With Amazon EMR on Amazon EKS, they gained a new option for running Spark jobs with the benefits of Kubernetes-based container orchestration, improved resource utilization, and faster job startup times. However, an HMS deployment supports only one authentication mechanism at a time. This means that they must configure Kerberos authentication for their Spark jobs on Amazon EMR on EKS to connect to the existing Kerberos-enabled HMS.

    In this post, we show how to configure Kerberos authentication for Spark jobs on Amazon EMR on EKS, authenticating against a Kerberos-enabled HMS so you can run both Amazon EMR on EC2 and Amazon EMR on EKS workloads against a single, secure HMS deployment.

    Overview of solution

    Consider an enterprise data platform team that’s been running Spark jobs on Amazon EMR on EC2 for several years. Their architecture includes a Kerberos-enabled standalone HMS that serves as the centralized data catalog, with Microsoft Active Directory functioning as the Key Distribution Center (KDC). As the team evaluates Amazon EMR on EKS for new workloads, their existing HMS must continue serving Amazon EMR on EC2, with both authenticating through the same Kerberos infrastructure. To address this, the platform team must configure their Spark jobs running on Amazon EMR on EKS to authenticate with the same KDC. This is so they can obtain valid Kerberos tickets and establish authenticated connections to the HMS while maintaining a unified security posture across their data platform.

    Architecture diagram showing two VPCs connected via VPC peering: the Active Directory VPC contains Microsoft Active Directory serving as the Kerberos Key Distribution Center (KDC) with ports 88 (Kerberos) and 749 (Admin). The Amazon EKS VPC contains two namespaces — the emr namespace runs Apache Spark jobs (each with a driver pod and executor pods) configured with krb5.conf, jaas.conf, and keytab files using a spark/analytics-team@CORP.KERBEROS principal; the hive-metastore namespace runs Hive Metastore pods (with deployment, replica set, and HPA) configured with Kerberos artifacts and the hive/hive-metastore@CORP.KERBEROS principal. Spark driver pods connect to the Hive Metastore service, which is backed by Amazon Aurora PostgreSQL for metadata storage and Amazon S3 for data storage. AWS Secrets Manager stores Kerberos keytabs and database credentials retrieved during deployment. Users submit Spark jobs via AWS Systems Manager Session Manager.

    Scope of Kerberos in this solution

    Kerberos authentication in this solution secures the connection between Spark jobs and the HMS. Other components in the architecture use AWS and Kubernetes security mechanisms instead.

    Solution architecture

    Our solution implements Kerberos authentication to secure the connection between Spark jobs and the HMS. The architecture spans two Amazon Virtual Private Clouds (Amazon VPCs) connected using VPC peering, with distinct components handling identity management, compute, and metadata services.

    Identity and Authentication layer

    A self-managed Microsoft Active Directory Domain Controller is deployed in a dedicated VPC and serves as the KDC for Kerberos authentication. The Active Directory server hosts service principals for both the HMS service and Spark jobs. This separate VPC deployment mirrors real-world enterprise architectures where Active Directory is typically managed by identity teams in their own network boundary, whether on-premises or in AWS.

    Data Platform layer

    The data platform components reside in a separate VPC and includes an EKS cluster that hosts both the HMS service and Amazon EMR on EKS based Spark jobs persisting data in an Amazon Simple Storage Service (Amazon S3) bucket.

    Hive Metastore service

    The HMS is deployed in the EKS hive-metastore namespace and simulates a pre-existing, standalone Kerberos-enabled HMS, a common enterprise pattern where HMS is managed independently of any data processing platform. You can learn more about other enterprise design patterns in the post Design patterns for implementing Hive Metastore for Amazon EMR or EKS. The HMS service authenticates with the KDC using its service principal and keytab mounted from a Kubernetes secret.

    Apache Spark Execution layer

    Apache Spark jobs are deployed using the Spark Operator on EKS. The Spark driver and executor pods are configured with Kerberos credentials through mounted ConfigMaps containing krb5.conf and jaas.conf, along with keytab files from Kubernetes secrets. When a Spark job must access Hive tables, the driver authenticates with the KDC and establishes a secure Simple Authentication and Security Layer (SASL) connection to the HMS.

    Authentication flow

    The HMS runs as a long-running Kubernetes service that must be deployed and authenticated before Spark jobs can connect.

    During HMS deployment:

    1. HMS pod validates its Kerberos configuration. krb5.conf and jaas.conf are mounted from ConfigMaps
    2. Service authenticates with KDC using its principal hive/hive-metastore-svc.hive-metastore.svc.cluster.local@CORP.KERBEROS
    3. keytab is mounted from Kubernetes secret for credential access
    4. Secure Thrift endpoint is established on port 9083 with SASL authentication enabled

    When a Spark job must interact with the HMS:

    1. Spark job submission:
      1. User submits Spark job through Spark Operator
      2. Driver and executor pods are created with Kerberos configuration mounted as volumes
      3. krb5.conf ConfigMap provides KDC connection details including realm and server addresses
      4. jaas.conf ConfigMap specifies a login module configuration with keytab path and principal
      5. Keytab secret contains encrypted credentials for Spark service principal spark/[email protected]
    2. Authentication and connection:
      1. Spark driver authenticates with KDC using its principal and keytab to obtain a Ticket Granting Ticket (TGT)
      2. When connecting to HMS, Spark requests a service ticket from the KDC for the HMS principal hive/hive-metastore-svc.hive-metastore.svc.cluster.local@CORP.KERBEROS
      3. KDC issues a service ticket encrypted with HMS’s secret key
      4. Spark presents this service TGT to HMS over the Thrift connection on port 9083
      5. HMS decrypts the ticket using its keytab, verifies Spark’s identity, and establishes the authenticated SASL session
      6. Executor pods use the same configuration for authenticated operations
    3. Data access:
      1. Authenticated Spark job queries HMS for table metadata
      2. HMS validates Kerberos tickets before serving metadata requests
      3. Spark accesses underlying data in Amazon S3 using IRSA

    Sequence diagram illustrating the Kerberos authentication flow between a Spark job and the Hive Metastore. The flow proceeds in five phases: (1) Job Submission — a Data Engineer submits a SparkApplication via kubectl, and the Spark Operator creates a driver pod with krb5.conf, jaas.conf, and keytab mounted. (2) Kerberos Authentication — the Spark driver loads its keytab for the spark/analytics-team@CORP.KERBEROS principal and sends an AS-REQ to the Active Directory KDC, which validates the credentials and returns a TGT (Ticket Granting Ticket). (3) Service Ticket Request — the Spark driver sends a TGS-REQ to the KDC requesting a service ticket for the Hive Metastore principal, and the KDC returns a service ticket encrypted with the HMS key. (4) Authenticated Connection — the Spark driver connects to the Hive Metastore over Thrift (port 9083) using SASL with the service ticket; HMS decrypts the ticket using its own keytab, verifies the Spark identity, and establishes an authenticated session. (5) Data Operations — the Spark driver queries table metadata from HMS (backed by Aurora PostgreSQL) and reads/writes table data directly from Amazon S3 using IRSA credentials.

    Implementation workflow

    The implementation involves three key stakeholders working together to establish the Kerberos-enabled communication:

    Microsoft Active Directory Administrator

    The Active Directory Administrator creates service accounts that are used for HMS and Spark jobs. This involves setting up the service principal names using the setspn utility and generating keytab files using ktpass for secure credential storage. The administrator configures the appropriate Active Directory permissions and Kerberos AES256 encryption type. Finally, the keytab files are uploaded to AWS Secrets Manager for secure distribution to Kubernetes workloads.

    Data Platform Team

    The platform team handles the Amazon EMR on EKS and Kubernetes configurations. They retrieve keytabs from Secrets Manager and create Kubernetes secrets for the workloads. They configure Helm charts for HMS deployment with Kerberos settings and set up ConfigMaps for krb5.conf, jaas.conf, and core-site.xml.

    Data Engineering Operations

    Data engineers submit jobs using the configured service account with Kerberos authentication. They monitor job execution and verify authenticated access to HMS.

    Deploy the solution

    In the remainder of this post, you will explore the implementation details for this solution. You can find the sample code in the AWS Samples GitHub repository. For additional details, including verification steps for each deployment stage, refer to the README in the repository.

    Prerequisites

    Before you deploy this solution, make sure that the following prerequisites are in place:

    Clone the repository and set up environment variables

    Clone the repository to your local machine and set the two environment variables. Replace <AWS_REGION> with the AWS Region where you want to deploy these resources.

    # Clone the Git repository
    git clone https://github.com/aws-samples/sample-emr-eks-spark-kerberos-hms.git
    cd sample-emr-eks-spark-kerberos-hms
    
    # Set environment variables
    export REPO_DIR=$(pwd)
    export AWS_REGION=<AWS_REGION>

    Setup Microsoft Active Directory infrastructure

    In this section, we deploy a self-managed Microsoft Active Directory with KDC on a Windows Server EC2 instance into a dedicated VPC. This is an intentionally minimal implementation highlighting only the key components required for this blog post.

    cd ${REPO_DIR}/microsoft-ad
    ./setup.sh

    Setup EKS infrastructure

    This section provisions the Amazon EMR on EKS infrastructure stack, including VPC, EKS cluster, Amazon Aurora PostgreSQL database, Amazon Elastic Container Registry (Amazon ECR), Amazon S3, Amazon EMR on EKS virtual clusters and the Spark Operator. Run the following script.

    cd ${REPO_DIR}/data-infra
    ./setup.sh

    Set up VPC peering

    This section establishes network connectivity between the Active Directory VPC and EKS VPC for Kerberos authentication. Run the following script:

    cd ${REPO_DIR}/vpc-peering
    ./setup.sh

    Deploy Hive Metastore with Kerberos authentication

    This section deploys a Kerberos-enabled HMS service on the EKS cluster. Complete the following steps:

    1. Create Kerberos Service Principal for HMS service
    cd ${REPO_DIR}/microsoft-ad/
    # Create HMS service principal
    ./manage-ad-service-principals.sh create hive "hive/hive-metastore-svc.hive-metastore.svc.cluster.local"
    # Verify the service principal was created
    ./manage-ad-service-principals.sh list
    1. Deploy HMS service with Kerberos authentication
    cd ${REPO_DIR}/hive-metastore
    ./deploy.sh

    Set up Amazon EMR on Amazon EKS with Kerberos authentication

    This section configures Spark jobs to authenticate with Kerberos-enabled HMS. This involves creating service principles for Spark jobs and generating the necessary configuration files. Complete the following steps:

    1. Create Service Principal for Spark jobs
    cd ${REPO_DIR}/microsoft-ad/
    # Create Spark service principal
    ./manage-ad-service-principals.sh create spark "spark/analytics-team"
    # Verify the service principal was created
    ./manage-ad-service-principals.sh list
    1. Generate Kerberos configurations for Spark jobs
    cd ${REPO_DIR}/spark-jobs/
    ./generate-spark-configs.sh --principal "spark/[email protected]" --namespace emr

    Submit Spark jobs

    This section verifies Kerberos authentication by running a Spark job that connects to the Kerberized HMS. Complete the following steps:

    1. Submit the test Spark job
    cd ${REPO_DIR}/spark-jobs
    kubectl apply -f spark-job.yaml
    1. Monitor job execution
    # Watch the SparkApplication status
    kubectl get sparkapplications -n emr -w
    # Check pod status
    kubectl get pods -n emr | grep "spark-kerberos"
    1. Verify Kerberos authentication and HMS connection
    # Check Spark driver logs for successful authentication
    kubectl logs spark-kerberos-job-driver -n emr

    The logs should confirm successful authentication, along with a listing of sample databases and tables.

    Understanding Kerberos configuration

    The HMS requires specific configuration parameters to enable Kerberos authentication, applied through the previously mentioned steps. The key configurations are outlined in the following section.

    HMS configuration (metastore-site.xml)

    The following configurations are added to metastore-site.xml file.

    Setting Value Purpose
    hive.metastore.sasl.enabled true Enable SASL authentication
    hive.metastore.kerberos.principal hive/hive-metastore-svc.hive-metastore.svc.cluster.local@CORP.KERBEROS HMS service principal
    hive.metastore.kerberos.keytab.file /etc/security/keytab/hive.keytab Keytab path

    Hadoop security (core-site.xml)

    The following configurations are added to the core-site.xml file.

    Setting Value
    hadoop.security.authentication kerberos
    hadoop.security.authorization true

    Spark configuration

    Setting Value Purpose
    spark.security.credentials.kerberos.enabled true Enable Kerberos for Spark
    spark.hadoop.hive.metastore.sasl.enabled true SASL for HMS connection
    spark.kerberos.principal spark/[email protected] Spark service principal
    spark.kerberos.keytab local:///etc/security/keytab/analytics-team.keytab Keytab path

    Shared Kerberos files

    Both HMS and Spark pods mount two common Kerberos configuration files: krb5.conf and jaas.conf, using ConfigMaps and Kubernetes secrets. The krb5.conf file is identical across both services and defines how each component connects to the KDC. The jaas.conf file follows the same structure but differs in the principal and keytab path for each service.

    1. krb5 Configuration
    [libdefaults]
    	default_realm = CORP.KERBEROS
    	dns_lookup_realm = false
    	dns_lookup_kdc = false
    	ticket_lifetime = 24h
    	forwardable = true
    	udp_preference_limit = 1
    	default_tkt_enctypes = aes256-cts-hmac-sha1-96 aes128-cts-hmac-sha1-96
    	default_tgs_enctypes = aes256-cts-hmac-sha1-96 aes128-cts-hmac-sha1-96
    	permitted_enctypes = aes256-cts-hmac-sha1-96 aes128-cts-hmac-sha1-96
    
    [realms]
    	CORP.KERBEROS = {
    		kdc = <ad-server-ip>
    		admin_server = <ad-server-ip>
    	}
    
    [domain_realm]
    	.corp.kerberos = CORP.KERBEROS
    	corp.kerberos = CORP.KERBEROS

    For more information, see the online documentation for krb5.conf.

    1. JAAS configuration
    Client {
     com.sun.security.auth.module.Krb5LoginModule required
     useKeyTab=true
     keyTab="/etc/security/keytab/hive.keytab"
     principal="hive/hive-metastore-svc.hive-metastore.svc.cluster.local@CORP.KERBEROS"
     useTicketCache=false
     storeKey=true
     debug=false;
    };
    

    Additional security considerations

    This post focuses on core Kerberos authentication mechanics between Spark and HMS. We recommend two additional security hardening steps based on your organization’s security posture and compliance requirements.

    Protecting Keytabs at Rest with AWS KMS Envelope Encryption

    Keytabs stored as Kubernetes Secrets are only base64-encoded by default, not encrypted at rest. We recommend enabling EKS envelope encryption using an AWS Key Management Service (AWS KMS) customer managed key. With envelope encryption, secret data is encrypted with a Data Encryption Key (DEK), which is encrypted by your customer managed key. This protects keytab content even if the etcd datastore is compromised. To enable this on an existing EKS cluster:

    aws eks associate-encryption-config \
      --cluster-name <your-cluster> \
      --encryption-config '[{"resources":["secrets"],"provider":{"keyArn":"arn:aws:kms:<region>:<account-id>:key/<key-id>"}}]'

    Refer to the Amazon EKS documentation on envelope encryption for full setup guidance.

    Encrypting the Thrift Data Channel with TLS

    SASL with Kerberos provides mutual authentication but doesn’t automatically encrypt data over the Thrift connection. Many deployments default to auth QoP, leaving the data channel unencrypted. We recommend either:

    • Set SASL QoP to auth-conf — enables SASL-layer encryption using Kerberos session keys
    • Layer TLS over Thrift (preferred) — enables transport-level encryption using modern cipher suites

    Enabling TLS on HiveServer2 / Hive Metastore Thrift:

    <property>
      <name>hive.server2.use.SSL</name>
      <value>true</value>
    </property>
    <property>
      <name>hive.server2.keystore.path</name>
      <value>/etc/tls/keystore.jks</value>
    </property>

    Refer to the Hive SSL/TLS configuration documentation for full details.

    Cleaning up

    To avoid incurring future charges, clean up all provisioned resources during this setup by executing the following cleanup script.

    cd ${REPO_DIR}/
    ./cleanup.sh

    Conclusion

    In this post, we demonstrated how to implement Kerberos authentication for Amazon EMR on EKS to securely connect to a Kerberos-enabled HMS. This solution addresses a common challenge faced by organizations with existing Kerberos-enabled HMS deployments who want to adopt Amazon EMR on EKS while maintaining their Kerberos-enabled security posture.

    This pattern applies whether you’re migrating from on-premises Hadoop, running hybrid Amazon EMR on EC2 or Amazon EMR on EKS environments, or building a new cloud-native platform. Any scenario where Spark jobs on Kerberos must authenticate with a shared, Kerberos-enabled HMS.

    You can use this post as a starting point to implement this pattern and extend it further to suit your organization’s data platform needs.


    About the authors

    Headshot of Krishna Kumar Venkateswaran

    Krishna Kumar Venkateswaran is a Cloud Infrastructure Architect at Amazon Web Services (AWS), passionate about building secure applications and data platforms. He has extensive experience in Kubernetes, DevOps, and enterprise architecture, helping customers containerize applications, streamline deployments, and optimize cloud-native environments.

    Headshot of Sunil Chakrapani Sundararaman

    Sunil Chakrapani Sundararaman is a DevOps Architect at Amazon Web Services (AWS), where he helps enterprise customers architect and implement Data and Machine Learning platforms in the AWS Cloud. He brings extensive experience in Data Platform engineering, MLOps, DevOps, and Kubernetes implementations. Sunil specializes in guiding organizations through their cloud transformation journey, focusing on building scalable and efficient solutions that drive business value.

    Headshot of Avinash Desireddy

    Avinash Desireddy is a Specialist Solutions Architect (Containers) at Amazon Web Services (AWS), passionate about building secure applications and data platforms. He has extensive experience in Kubernetes, DevOps, and enterprise architecture, helping customers and partners containerize applications, streamline deployments, and optimize cloud-native environments.

    Headshot of Suvojit Dasgupta

    Suvojit Dasgupta is an Engineering Leader at Amazon Web Services (AWS). He leads engineering teams, guiding them in designing and implementing scalable, high-performance data platforms for AWS customers. With expertise spanning distributed systems, real-time and batch data architectures, and cloud-native infrastructure, he drives technical strategy and engineering excellence across teams. He is passionate about raising the bar on engineering practices, and solving large-scale problems at the intersection of data and business impact.

    Building Memory-Intensive Apps with AWS Lambda Managed Instances

    Post Syndicated from Guy Haddad original https://aws.amazon.com/blogs/compute/building-memory-intensive-apps-with-aws-lambda-managed-instances/

    Building memory-intensive applications with AWS Lambda just got easier. AWS Lambda Managed Instances gives you up to 32 GB of memory—3x more than standard AWS Lambda—while maintaining the serverless experience you know. Modern applications increasingly require substantial memory resources to process large datasets, perform complex analytics, and deliver real-time insights for use cases such as in-memory analytics, Machine Learning (ML) model inference, and real-time semantic search. AWS Lambda Managed Instances gives you a familiar serverless programming model and experience combined with the flexibility of being able to choose the underlying Amazon EC2 instance types and providing developers with access to large memory configurations.

    In this post, you will see how AWS Lambda Managed Instances enables memory-intensive workloads that were previously challenging to run in serverless environments, using an AI-powered customer analytics application as a practical example. You’ll see cost savings of up to 33% compared to standard Lambda for predictable workloads, while eliminating the operational overhead of managing EC2 instances.

    Understanding AWS Lambda Managed Instances

    AWS Lambda Managed Instances runs your AWS Lambda functions on the Amazon EC2 instance types of your choice in your account, including Graviton4 and memory-optimized instance types. AWS handles underlying infrastructure lifecycle including provisioning, scaling, patching, and routing, while you benefit from Amazon EC2 pricing advantages like Savings Plans and Reserved Instances.

    Key benefits include:

    • Flexible instance selection: Choose from compute-optimized (C), general-purpose (M), and memory-optimized (R) instance families
    • Configurable memory-CPU ratios: Optimize resource allocation for your workload
    • Multi-concurrent invocations: One execution environment handles multiple invocations simultaneously, improving utilization for I/O-heavy applications
    • Dynamic scaling: Instances scale based on CPU utilization without cold starts

    AWS Lambda Managed Instances is best suited for high-volume, predictable workloads that benefit from sustained compute capacity and larger memory configurations.

    Memory-Intensive Workloads Work Best with AWS Lambda Managed Instances

    This blog focuses on one of AWS Lambda Managed Instances’ most powerful capabilities: running memory-intensive workloads that require more than the standard AWS Lambda’s 10 GB memory and 250MB ZIP limits. Here are the use cases where AWS Lambda Managed Instances helps:

    • In-Memory Analytics — Load gigabytes of structured data into memory at initialization and serve sub-millisecond analytical queries across thousands of invocations
    • ML Model Inference — Keep large model weights resident in memory across invocations for consistent, low-latency inference without a dedicated endpoint.
    • Real-Time Semantic Search — Build vector similarity search over large embedding indexes held entirely in memory, enabling natural language queries over millions of records without an external vector database.
    • Graph Processing — Hold large graph structures in memory for traversal algorithms that require the full graph to be accessible at once.
    • Scientific & Numerical Computing — Run simulations, Monte Carlo methods, and large matrix operations that require substantial working memory and benefit from memory-optimized Amazon EC2 instance families.
    • Large-Scale Report Generation — Aggregate and transform multi-gigabyte datasets in memory to generate complex reports or dashboards on demand, without staging data through intermediate storage.

    Use Case: AI-Powered Customer Analytics with AWS Lambda Managed Instances

    To demonstrate the power of AWS Lambda Managed Instances for memory-intensive applications, we built an AI-Powered Customer Analytics application that combines in-memory data processing with ML-based semantic search. The application loads in memory 1 million customer behavioral records (sessions, purchases, browsing patterns) from a Parquet file in S3 into a Pandas DataFrame and an embeddings cache consuming 200MB, then responds for analytics queries:

    1. Customer Analysis — Deep-dive into individual customer behavior: engagement scores, conversion rates, purchase patterns, and AI-generated customer segments
    2. Semantic Search — Natural language queries powered by FastEmbed (sentence-transformers/all-MiniLM-L6-v2) that find similar customers using vector similarity
    3. Cohort Analysis — Real-time segmentation by device, country, age group with aggregated metrics

    Architecture Overview

    Our AI-powered customer analytics application demonstrates this in practice: 1 million records in memory (200MB), a compact sentence transformer model for semantic search, sub-second query performance, and zero infrastructure to manage. The solution uses a simple, serverless architecture:

    • Customer transaction data (Parquet format) is stored in Amazon S3
    • Amazon Cognito User Pool authenticates users and issues JWT tokens for API access
    • Amazon API Gateway routes requests with Cognito authorizer validation, rate limiting (5 requests/second, burst 10), X-Ray tracing, and access logging
    • AWS Lambda function with AWS Lambda Managed Instances loads the entire dataset (200MB) and all-MiniLM-L6-v2 model (900MB) into memory during initialization while also performing a threaded embeddings cache generation. This step can consume about 14GB of the allocated memory, exceeding standard AWS Lambda’s 10 GB limit
    • Analytics queries execute against the in-memory data using the model
    • Results are returned in milliseconds for interactive analysis

    Architecture diagram

    Deploy the Application

    The below steps walk you through deploying the application to AWS using the AWS Serverless Application Model (SAM). The deployment process packages your Lambda function code, uploads artifacts to Amazon S3, and provisions all required AWS resources including Lambda functions, IAM roles, and any configured VPC networking via AWS CloudFormation.

    Prerequisites

    Make sure you have the following tools installed locally:

    • AWS CLI configured with credentials
    • SAM CLI installed
    • Python 3.13+ installed locally
    • Docker or Finch (required for container builds)
    • AWS account with appropriate permissions
    • A VPC with at least 2 subnets (across different Availability Zones) and a security group — required for the Lambda Managed Instances capacity provider
    • Supported regions: Check AWS Capabilities by Region for supported regions

    Getting Started

    The complete source code for this application is available in our GitHub repository. To deploy it yourself follow the below steps and refer to the full deployment instructions hosted on GitHub.

    1. Clone the repository

    git clone https://github.com/aws-samples/sample-lambda-managed-instances-analytics.git

    2. Navigate to the project folder

    cd sample-lambda-managed-instances-analytics

    chmod +x setup-data.sh deploy-lambda.sh

    3. Generate sample data and upload to S3

    ./setup-data.sh

    This script will create an S3 bucket (if needed), generate 1M rows of sample data, and upload the data to S3.

    4. Build and deploy the Lambda function

    ./deploy-lambda.sh

    This script will build the container image with FastEmbed, push it to ECR, and deploy the Lambda function along with Capacity Provider, API Gateway, and Cognito User Pool. After deployment, it automatically generates the UI authentication configuration and prompts you to create a test user.

    SAM template

    Capacity provider configuration

    Run the Application

    1. Start the UI

    The application includes a simple HTML-based UI through which you can test the AWS Lambda function using Amazon API Gateway:

    cd ui && python3 -m http.server 8000

    2. Open your browser at http://localhost:8000 and click ‘Sign In’ to authenticate via Cognito using the username/password that you created during deployment

    Starting the UI

    3. Enter your API endpoint URL. Test connection and click system Info.

    Testing the connection

    Test the Application

    a. Customer Analysis — Enter one or more User IDs to get more information on the customer behavior: engagement scores, conversion rates, purchase patterns, and AI-generated customer segments

    Running customer analysis

    b. Semantic Search – Enter natural language queries like “list high value customers from USA” in the Semantic Search and verify the results. Note that the response is very fast as the analytics data and FastEmbed models are loaded into memory during init stage

    Running semantic search

    c. Cohort Analysis — Enter the query data to get Real-time segmentation by device, country, age group with aggregated metrics

    Running cohort analysis

    Observability

    AWS Lambda Managed Instances automatically publishes metrics to Amazon CloudWatch, giving you visibility into function performance and capacity utilization. Monitor InitDuration to track dataset and model load time at startup, MaxMemoryUsed to confirm your data fits within configured memory, and ProvisionedConcurrencySpilloverInvocations to detect when AWS Lambda Managed Instances capacity is exhausted.

    Enable AWS Lambda Insights for enhanced per-invocation metrics including CPU time and memory utilization over time. Use Amazon CloudWatch Log Insights to query INIT_START, INIT_END, and REPORT log entries for initialization and memory details per invocation.

    AWS Lambda Insights

    What Makes This Better with AWS Lambda Managed Instances

    Without AWS Lambda Managed Instances, building this same application would require one of these alternatives:

    • Option A: EC2 with auto-scaling — Full control, full responsibility: patching, scaling policies, load balancing, and deployment pipelines — all on you.
    • Option B: Redesign for standard Lambda — Swap in-memory data for an external database and replace the ML model with Amazon SageMaker endpoint. More latency, more cost, more complexity.

    With AWS Lambda Managed Instances, you write a single AWS Lambda function, define a Capacity Provider, and deploy with SAM. AWS Lambda handles the Amazon EC2 instances, scaling, and lifecycle, giving you the memory you need with the operational simplicity you want. The in-memory approach eliminates network latency and disk I/O, delivering consistent sub-200ms response times for complex analytics.

    Cost Considerations

    AWS Lambda Managed Instances uses Amazon EC2-based pricing with a management fee. For predictable workloads, you can leverage Amazon EC2 Savings Plans or Reserved Instances to reduce costs significantly.

    Example cost comparison (us-east-1, 32 GB memory, 1M invocations/month):

    • AWS Lambda (standard): ~$267/month (on-demand pricing)
    • AWS Lambda Managed Instances: ~$180/month (with 1-year Compute Savings Plan)
    • Savings: 33% reduction

    The cost benefits increase with higher memory configurations and sustained workloads that can take advantage of Amazon EC2 pricing discounts.

    Best Practices

    Based on experience building this solution, here are key recommendations:

    • Memory sizing: Start with your dataset size plus 50% overhead for processing. Monitor Amazon CloudWatch metrics to optimize.
    • Initialization strategy: Load large datasets during the init phase to amortize the cost across multiple invocations.
    • Concurrency configuration: Set PerExecutionEnvironmentMaxConcurrency based on your workload’s I/O characteristics. Higher values work well for I/O-bound analytics.
    • Data format: Use columnar formats like Parquet for efficient memory usage and fast loading.
    • Monitoring: Track initialization duration, memory utilization, and invocation latency in Amazon CloudWatch to identify optimization opportunities.

    Cleanup

    When you’re done exploring the solution, it’s good practice to remove all provisioned resources to avoid ongoing charges. For the full cleanup commands and exact steps, refer to the project’s README.md in GitHub repository.

    Conclusion

    AWS Lambda Managed Instances opens up a new class of serverless applications that support larger AWS Lambda layer packages and more memory. Memory-intensive workloads — in-memory analytics, ML inference, graph processing, scientific computing — can now run with the simplicity of AWS Lambda and the resources of Amazon EC2. The customer analytics example demonstrates how in-memory processing with AWS Lambda Managed Instances delivers performance improvements over traditional database queries while maintaining serverless benefits like automatic scaling and pay-per-use pricing.

    Ready to get started? Explore the AWS Lambda Managed Instances documentation and try building your own memory-intensive serverless application. You can find the complete code for this example on GitHub.

    Build a multi-tenant configuration system with tagged storage patterns

    Post Syndicated from Koshal Agrawal original https://aws.amazon.com/blogs/architecture/build-a-multi-tenant-configuration-system-with-tagged-storage-patterns/

    In modern microservices architectures, configuration management remains one of the most challenging operational concerns. Two gaps emerge as organizations scale: handling tenant metadata that changes faster than cache TTL allows, and scaling the metadata service itself without creating a performance bottleneck.

    Traditional caching strategies force an uncomfortable trade-off: either accept stale tenant context (risking incorrect data isolation or feature flags), or implement aggressive cache invalidation that sacrifices performance and increases load on your metadata service. When tenant counts grow into the hundreds or thousands, this metadata service itself becomes a scaling challenge, particularly when different configuration types have vastly different access patterns.

    The challenge intensifies when you need to support different storage backends for different configuration types. Some require high-frequency access patterns suited for Amazon DynamoDB, while others benefit from the hierarchical organization and built-in versioning of AWS Systems Manager Parameter Store. Traditional solutions often force engineering teams into a corner: either build multiple configuration services (increasing operational overhead), or compromise on performance by using a single storage backend that isn’t optimized for every use case.

    In this post, we demonstrate how you can build a scalable, multi-tenant configuration service using the tagged storage pattern, an architectural approach that uses key prefixes (like tenant_config_ or param_config_) to automatically route configuration requests to the most appropriate AWS storage service. This pattern maintains strict tenant isolation and supports real-time, zero-downtime configuration updates through event-driven architecture, alleviating the cache staleness problem.

    What you’ll learn:

    • Implementing a multi-tenant data model with DynamoDB and Parameter Store
    • Using the Strategy pattern for flexible storage backend switching
    • Building tenant isolation through JSON Web Token (JWT) claims
    • Creating an event-driven auto-refresh mechanism with Amazon EventBridge and AWS Lambda
    • Implementing zero-downtime configuration updates with gRPC (a high-performance communication protocol) streaming
    • Addressing the cache TTL problem for rapidly-changing tenant metadata

    By the end of this post, you’ll understand how to architect a configuration service that handles complex multi-tenant requirements while optimizing for both performance and operational simplicity.

    Solution overview

    The architecture uses four AWS services orchestrated through a NestJS-based gRPC service to create a reliable, event-driven configuration management system. Let’s first understand the overall architecture before diving into each component’s implementation details.

    Architecture components

    The following diagram shows the end-to-end architecture of the Multi-Tenant Configuration Service deployed on AWS, from how client requests enter the system to how configuration data is retrieved from the right storage backend.

    WS microservices architecture diagram showing ECS Fargate services, API Gateway, Cognito auth, DynamoDB, and CloudWatch monitoring

    Figure 1: Multi-Tenant Configuration Service Architecture

    Client applications authenticate via Amazon Cognito and pass through AWS WAF before reaching Amazon API Gateway. Traffic is then routed through a VPC Link to an Application Load Balancer, which distributes requests across two core microservices running on Amazon Elastic Container Service (Amazon ECS) on AWS Fargate within private subnets :

    • Order Service— handles incoming REST requests and delegates configuration lookups to the Config Service via gRPC
    • Config Service— exposes a gRPC API and uses a Config Strategy Factory to dynamically select the appropriate storage backend (DynamoDB or Parameter Store) based on the request

    Service discovery is managed by AWS Cloud Map, while Amazon CloudWatch centralizes logs and metrics across services.

    The system is organized into four interconnected layers, each addressing a specific aspect of the configuration management challenge:

    1. Storage layer – multi-backend strategy

    The storage layer strategically uses two complementary AWS services, each optimized for different configuration access patterns and requirements.

    • Amazon DynamoDB: Stores tenant-specific configurations. These are settings unique to each customer, such as payment gateway preferences or feature flags. With single-digit millisecond latency, DynamoDB handles high-frequency reads efficiently. The schema uses composite keys (TENANT#{tenantId} as partition key, CONFIG#{configType} as sort key) for efficient tenant-scoped queries and built-in multi-tenant isolation at the data model level.
    • AWS Systems Manager Parameter Store: manages shared parameters. These are configuration values used across multiple services or tenants, such as API endpoints, database connection strings, and region-specific settings. Unlike tenant-specific configs that change frequently, these parameters are relatively static but benefit from hierarchical organization. The path structure (/config-service/{tenantId}/{service}/{parameter}) enables bulk retrieval operations, reducing the number of API calls needed during service initialization from dozens to a single request.

    2. Service layer – gRPC with strategy pattern

    A NestJS-based microservice implements the configuration retrieval logic using gRPC for high-performance, type-safe communication. This choice significantly reduces network bandwidth and improves response times for service-to-service communication where compatibility with web browsers isn’t a requirement.

    At the core is a Strategy Pattern implementation that determines the optimal storage backend based on configuration key prefixes. This pattern simplifies the addition of new storage backends (like Amazon Simple Storage Service (Amazon S3) for large configuration files) without modifying the core service logic.

    3. Authentication layer – Amazon Cognito

    User authentication flows through Amazon Cognito with custom attributes:

    • custom:tenantId (immutable) – Tenant identifier embedded in JWT
    • custom:role (mutable) – User role for authorization

    Critical security design: The service never accepts tenantId from request parameters. Instead, it extracts the tenant context from validated JWT tokens, making sure requests cannot access other tenants’ data even if they attempt to manipulate request payloads.

    4. Event-driven refresh layer

    Traditional configuration updates present a dilemma: how do you keep services synchronized without compromising performance or causing downtime?

    Polling approaches continuously check for changes, generating unnecessary API calls that cost money even when nothing changes. They also introduce delays. Services don’t see updates until the next poll cycle, which could be seconds or minutes later.

    Service restart approaches cause downtime, drop active connections, and disrupt user sessions. For SaaS applications serving customers 24/7, restart-based updates are unacceptable.

    The event-driven refresh layer addresses both problems by implementing a reactive architecture where Amazon EventBridge monitors Parameter Store for changes and triggers AWS Lambda to update the service’s local cache. This achieves configuration updates within seconds while users experience no interruption.

    Technical implementation

    The following sections detail the implementation, starting with the data model, which serves as the backbone for tenant isolation and efficient querying.

    A. Multi-tenant data model

    The foundation of tenant isolation begins with the data model. Using DynamoDB’s composite key structure, we achieve both tenant isolation and efficient querying without requiring separate tables per tenant.

    DynamoDB schema design:

    The following example shows a tenant-specific configuration stored in DynamoDB, illustrating how composite keys enable both isolation and efficient access:

    {
      "pk": "TENANT#acme-corp",
      "sk": "CONFIG#payment-gateway",
      "config": {
        "providers": [
          {
            "name": "Stripe",
            "apiEndpoint": "https://api.stripe.com",
            "retryPolicy": "exponential"
          }
        ]
      },
      "isActive": true,
      "version": 2,
      "createdAt": "2024-01-15T10:30:00Z",
      "updatedAt": "2024-02-20T14:45:00Z"
    }

    Key schema decisions:

    1. Partition key pattern: TENANT#{tenantId} makes sure tenant data is co-located, enabling efficient tenant-scoped queries while maintaining logical separation.
    2. Sort key pattern: CONFIG#{configType} allows querying specific configuration types within a tenant’s data. The CONFIG# prefix enables future expansion with other entity types (for example, METADATA#, AUDIT#).
    3. Soft deletion: The isActive boolean flag supports soft deletion, maintaining audit trails while excluding inactive configurations from queries.
    4. Versioning: The version field tracks configuration changes, supporting rollback capabilities and change history.

    Parameter store organization:

    Parameters follow a hierarchical structure that mirrors the multi-tenant model. This example demonstrates the path structure:

    /config-service/
    ├── acme-corp/
    │   ├── api/
    │   │   ├── api-key
    │   │   └── endpoint
    │   └── database/
    │       └── connection-string
    └── globex-inc/
        ├── api/
        │   ├── api-key
        │   └── endpoint
        └── database/
            └── connection-string

    This structure provides several benefits:

    • Bulk retrieval using path prefix (GetParametersByPath API)
    • Clear ownership and access control through AWS Identity and Access Management (AWS IAM) policies
    • Environment separation (dev/staging/prod) at the path level
    • Automatic parameter versioning and change tracking

    Advanced: Multi-dimensional tenant context
    For organizations with multiple services requiring different configuration scopes, consider introducing a second dimension in the partition key:

    PK = "TENANT#acme-corp|SERVICE#order-service"
    SK = "CONFIG#payment-gateway"

    This multi-dimensional approach enables service-level isolation where the Order service sees only billing API configurations while the Reporting service doesn’t have access to payment gateway settings. It also provides efficient service-scoped queries, retrieve configurations for a specific service with PK = TENANT#acme-corp|SERVICE#order-service and SK begins with CONFIG#. The second dimension can represent business units, geographic regions, or a logical boundary that aligns with access control requirements, making this pattern particularly valuable when fine-grained access control beyond tenant-level isolation is needed. For detailed guidance on multi-tenant DynamoDB modelling patterns, see amazon-dynamodb-data-modeling-for-multi-tenancy-part-2.

    B. Strategy pattern for storage flexibility

    The system decides which storage backend to use for each configuration request. The Strategy Pattern is a design approach that allows a program to choose different behaviors at runtime based on context. Think of it like a traffic controller that examines each request and directs it to the appropriate service.

    Why use the strategy pattern?

    Without the Strategy Pattern, handling multiple storage backends would require complex conditional logic throughout the code base. Different tenant metadata has vastly different access patterns. Routing to optimized backends alleviates both DynamoDB cost explosions (for rarely-changing configs) and Parameter Store throttling (for high-frequency reads), addressing the scaling gap. A naive implementation might look something like this and it’s worth pausing to understand why this approach breaks down.

    // Without Strategy Pattern - complex and hard to maintain
    async getConfig(key: string, tenantId: string) {
      if (key.startsWith('tenant_config_')) {
        // DynamoDB logic here
        const pk = `TENANT#${tenantId}`;
        const sk = `CONFIG#${key.slice(14)}`;
        return await this.dynamoDB.query({...});
      } else if (key.startsWith('param_config_')) {
        // Parameter Store logic here
        const path = `/config-service/${tenantId}/${key.slice(13)}`;
        return await this.ssm.getParameter({...});
      }
      // More conditions as backends are added...
    }

    Every time you add a new storage backend, say, AWS Secrets Manager or Amazon S3, you’re forced to reach back into this function and bolt on another else if. The storage logic becomes tightly coupled to your service layer, making it harder to test each backend in isolation and nearly impossible to swap one out without risking regressions elsewhere.

    Implementation strategy

    The Strategy Pattern encapsulates storage-specific logic into separate, interchangeable strategy classes. This code demonstrates how the factory examines keys and selects strategies:

    @Injectable()
    export class ConfigStrategyFactory {
      private keyStrategyMap = new Map<string, ConfigStrategy>([
        ['tenant_config_', this.dynamoDBConfigStrategy],
        ['param_config_', this.ssmConfigStrategy],
      ]);
      getStrategy(key: string): ConfigStrategy {
        for (const [prefix, strategy] of this.keyStrategyMap.entries()) {
          if (key.startsWith(prefix)) {
            return strategy;
          }
        }
        throw new ValidationException(`Invalid key format: ${key}`);
      }
    }

    Key prefix mapping:

    • tenant_config_* → Routes to Amazon DynamoDB for tenant-specific, high-frequency access patterns
    • param_config_* → Routes to AWS Systems Manager Parameter Store for shared, hierarchical parameters

    With this approach, adding a new storage backend requires only:

    • Creating a new strategy class implementing the ConfigStrategy interface
    • Adding one line to the keyStrategyMap with the new prefix and strategy
    • No changes to existing strategies or calling code

    This design helps protect technology investments. As requirements evolve and new AWS services become relevant, the system adapts without major rewrites.

    Multi-layer caching strategy

    Different configurations benefit from different caching approaches. The pattern implements different caching strategies optimized for each configuration type’s access patterns and business requirements:

    • High-frequency tenant configurations (accessed thousands of times per minute) use application-level caching with short Time-To-Live (TTL) values. This significantly reduces database queries while maintaining reasonably fresh data.
    • Shared parameters (accessed frequently but change rarely) use in-memory caching with event-driven invalidation. The cache only refreshes when EventBridge detects an actual change, alleviating unnecessary API calls.

    Cache Security Considerations

    The implementation uses a shared in-memory Map with tenant-prefixed keys (tenantId:serviceName:configKey). Cached values are configuration metadata (API endpoints, feature flags, thresholds), not sensitive data like credentials or PII. Sensitive values remain in Parameter Store with SecureString encryption and are retrieved on-demand, not cached. Even in edge cases, downstream access controls (JWT validation, DynamoDB composite keys) act as the final enforcement boundary.

    For teams handling more sensitive configuration payloads, consider Amazon ElastiCache (Redis OSS) or Valkey with key-prefix isolation and encryption at rest/in transit, though this adds 1-3ms network latency versus sub-millisecond in-memory access.

    C. Authentication and tenant isolation

    Tenant isolation is enforced at multiple layers, starting with JWT-based authentication and custom authorization guards.

    Cognito JWT validation flow:

    1. Client authenticates with Cognito and receives JWT token
    2. Request includes JWT in Authorization: Bearer {token} header
    3. CognitoJwtGuard validates token signature against Cognito JSON Web Key Sets (JWKS) endpoint
    4. Guard extracts custom:tenantId claim and attaches to request context
    5. TenantAccessGuard verifies user has access to requested tenant
    6. Service layer uses validated tenantId for data operations

    This implementation demonstrates the secure approach to tenant context extraction:

    async retrieveConfig(req: RetrieveConfigRequest): Promise<RetrieveConfigResponse> {
      // tenantId is extracted from validated JWT token, never from request parameters
      const tenantId = (req as any).tenantId;
      if (!tenantId) {
        throw new UnauthorizedException('Tenant ID not found in authentication context');
      }
      const strategy = this.strategyFactory.getStrategy(req.key);
      const data = await strategy.getConfig(req.serviceName, req.key, tenantId);
      return { data };
    }

    Why this approach helps prevent unauthorized access:

    Consider what happens if an unauthorized user tries to access another tenant’s configuration:

    1. User authenticates as Tenant A and receives JWT with custom:tenantId: "tenant-a"
    2. User attempts to manipulate request to access Tenant B’s data
    3. The service extracts tenantId from the JWT (still “tenant-a”), ignoring request parameters
    4. Query uses the JWT’s tenant ID, so user only sees Tenant A’s data

    Advanced: Infrastructure-level credential isolation

    The current design enforces tenant isolation at the application layer through JWT extraction and DynamoDB composite keys. The ECS task uses a shared IAM execution role, meaning tenant requests operate under the same AWS credentials. While this approach is sufficient for most multi-tenant applications, teams with stricter compliance requirements (HIPAA, PCI-DSS, FedRAMP) may need infrastructure-level isolation.

    For enhanced isolation, consider implementing a Token Vending Machine (TVM) pattern with AWS Security Token Service (STS) to issue temporary, tenant-scoped IAM credentials. This provides infrastructure-level isolation with per-tenant AWS CloudTrail audit trails and principle of least privilege enforcement. However, TVM adds operational complexity (credential caching, STS API costs, token refresh logic) and latency (50-100ms per operation).

    Consider this as a next step when compliance auditors require infrastructure-level separation rather than a baseline requirement.

    This design helps prevent cross-tenant access attempts at the infrastructure level, addressing a common security issue.

    D. Zero-downtime auto-refresh mechanism

    Configuration updates in production systems present a classic operations challenge. This event-driven approach addresses the cache TTL trade-off entirely, configurations update in real-time without polling or staleness windows.

    EventBridge integration flow:

    1. Parameter Store Change
             ↓
    2. EventBridge Rule (matches /config-service/* changes)
             ↓
    3. Lambda Function (extracts tenantId from path)
             ↓
    4. Service Discovery (AWS Cloud Map queries for healthy instances)
             ↓
    5. gRPC Refresh Call (direct service-to-service invocation)
             ↓
    6. In-Memory Cache Update (zero-downtime)
             ↓
    7. Updated Configuration Active (no connection drops)

    Key benefits:

    1. Zero downtime: No service restarts required. Connections remain active
    2. Reactive updates: Only triggers when changes occur (no wasteful polling)
    3. Cost efficient: Minimizes SSM API calls through caching and event-driven refresh
    4. Audit trail: EventBridge provides complete change history and monitoring

    When to use this pattern?

    The tagged storage pattern isn’t universally applicable. Like most architectural approaches, it has ideal use cases where the benefits significantly outweigh the implementation complexity. Consider this pattern when your application matches these characteristics:

    • Multi-tenant SaaS requiring strict tenant isolation and regulatory compliance benefit significantly. The pattern’s infrastructure-level isolation through JWT claims and data model design provides security commitments that application-level isolation cannot match.
    • Microservices architectures with complex configuration requirements across dozens of services find value in the centralized management and flexible storage routing.
    • Organizations managing configurations across multiple storage backends and environments (dev, staging, production, DR) appreciate the hierarchical organization and path-based access control that Parameter Store provides, combined with DynamoDB’s performance for high-frequency access.
    • High-throughput applications (1000+ requests/second) needing sub-millisecond response times use DynamoDB Accelerator (DAX) for in-memory caching. While DynamoDB offers excellent single-digit millisecond latency, DAX delivers microsecond read latency, typically 5-10x faster for cached data. This makes a substantial difference at scale.
    • Teams prioritizing operational simplicity value the event-driven refresh mechanism that avoids manual deployment coordination.

    Getting started

    Ready to implement the Tagged Storage Pattern in your organization?

    Start with a pilot project focusing on a single microservice and gradually expand the pattern across your architecture. The modular design means that you can realize benefits incrementally while building confidence in the approach.

    Implementation steps:

    1. Design your data model: Define DynamoDB schema and Parameter Store hierarchy
    2. Set up Amazon Cognito: Configure user pool with custom tenant attributes
    3. Build the service layer: Implement Strategy Pattern for storage routing
    4. Add event-driven refresh: Configure EventBridge rules and Lambda function
    5. Test tenant isolation: Verify JWT validation and cross-tenant access deterrence
    6. Deploy and monitor: Establish CloudWatch dashboards and operational procedures

    You can find the complete code for this solution, including AWS CloudFormation templates, deployment and testing scripts, in the GitHub – Configuration Management Service.

    To avoid incurring ongoing charges, delete the resources you created during this walkthrough. For detailed cleanup instructions including step-by-step commands and verification steps, see the Infrastructure Cleanup Guide.

    Conclusion

    Building a multi-tenant configuration service requires careful consideration of storage patterns, security boundaries, and operational requirements. The tagged storage pattern demonstrated in this post provides a flexible, scalable foundation that addresses these challenges through:

    1. Intelligent storage routing: The Strategy Pattern provides optimal backend selection per configuration type, allowing DynamoDB for tenant-specific settings and SSM Parameter Store for shared parameters.
    2. Zero-downtime updates: Event-driven architecture through EventBridge and Lambda avoids service restarts and polling overhead so that configurations refresh immediately upon changes.
    3. Strong tenant isolation: JWT-based authentication with custom claims makes sure tenant boundaries are enforced at the infrastructure level, not application logic, helping prevent cross-tenant access attempts.
    4. Operational simplicity: In-memory caching, combined with event-driven refresh, can reduce API costs while maintaining microsecond response times.
    5. Cost efficiency: Pay-per-request billing, aggressive caching, and Spot instances help keep operational costs minimal even at scale.

    Additional resources


    About the authors

    A framework for securely collecting forensic artifacts into S3 buckets

    Post Syndicated from Jason Garman original https://aws.amazon.com/blogs/security/a-framework-for-securely-collecting-forensic-artifacts-into-s3-buckets/

    When customers experience a security incident, they need to acquire forensic artifacts to identify root cause, extract indicators of compromise (IoCs), and validate remediation efforts. NIST 800-86, Guide to Integrating Forensic Techniques into Incident Response, defines digital forensics as a process comprised of four basic phases: collection, examination, analysis, and reporting. This blog post focuses on the first phase—collection—and provides best practices for implementing least privilege during the forensic evidence collection processes that collect evidence and store the artifacts in Amazon Simple Storage Service (Amazon S3) buckets. The architecture presented in this post can be used to collect forensic evidence from both Amazon Web Services (AWS) and non-AWS compute resources.

    It’s important to consider the security of the forensic artifact collection process because it involves communicating with potentially compromised resources. The collection methodology itself should be designed to avoid adding additional risks to infrastructure or other forensic investigation processes. At the same time, the collection of forensic artifacts requires the use of specialized tools that are difficult to change or adapt to new security requirements.

    This post outlines factors that you should consider when creating an evidence collection capability and introduces an architecture that implements the best practices for least privilege and integrating with (instead of changing or adapting) existing forensic tools that support uploading artifacts to S3 buckets by using AWS security credentials.

    Solution architecture

    The architecture presented in this post demonstrates the following AWS best practices:

    1. Least privilege – Use AWS Identity and Access Management (IAM) policies to provide least privilege access to upload forensic artifacts to an S3 location dedicated to a specific forensic collection task. The locked down credentials cannot be used to view or modify any other forensic collections.
    2. Time-limited credentials – Use AWS Security Token Service (AWS STS) to provide time limited credentials, reducing the potential for an unauthorized user to abuse credentials while they’re visible on the target machine during the artifact collection process.
    3. Compatibility with third-party tools – Forensic tools are specialized and changing a forensic collection process to adapt to different collection methods might not be possible. To avoid the risk of needing to change tools, maximize compatibility with any third-party tools that support uploading to S3 buckets. The method introduced in this post to generate time-limited, scoped down credentials can be used with most third-party forensic tools that support uploading to S3 buckets.
    4. Credential vending – Use time-limited tokens, which can be vended on demand through an automated process, eliminating the need for forensic investigators to use the AWS Management Console, understand least privilege, or have any access to the AWS control plane. Forensic investigators can focus on the process of collecting and analyzing evidence.
    5. Process automation – Deploy the process as infrastructure as code (IaC) and automate it through AWS services, reducing the burden on security teams to manually perform runbook steps during an active security incident.

    This post starts with an overview of the digital forensic process, provides best practices for using Amazon S3 to store forensic artifacts, details how you can create time-limited, least privilege tokens to provide secure access to upload forensic artifacts to S3 buckets, and introduces a sample architecture that automates the end-to-end process.

    The digital forensic process

    Organizations need to have practices and resources in place to support a digital forensic investigation environment before an incident occurs. AWS has published several resources, including Forensic investigation environment strategies in the AWS Cloud and AWS prescriptive guidance: Security Reference Architecture, Cyber forensics, to provide best practices for organizing your AWS accounts using AWS Organizations to support forensic clean-room environments. Creating segregated AWS accounts and resources for your security teams is critical to provide your incident responders a location to store and analyze any digital forensic evidence collected during an investigation.

    After you’ve established a landing zone for performing digital forensics, you’re ready to collect and process digital forensic evidence. AWS supports the collection of digital forensics through extensive logging of control plane events in AWS CloudTrail, and metrics and application logs that can be stored in Amazon CloudWatch. In addition, AWS core compute services, such as Amazon Elastic Compute Cloud (Amazon EC2), support forensics operations through snapshots of the underlying Amazon Elastic Block Storage (Amazon EBS) volume. An example architecture to demonstrate how to automate the collection of EBS volume snapshots for forensic investigations can be found in How to automate forensic disk collection in AWS.

    You might want to use the same AWS infrastructure to collect, examine, analyze, and report on forensic incidents that occur on other resources, such as corporate laptops. You can use existing forensic tooling to perform live response, collecting specific artifacts such as Windows NT File System (NTFS) Master File Table (MFT), logs from Linux machines, volatile memory images, or other artifacts that are specified as part of your organization’s incident response plan. These tools can be provided by third parties or built in-house, and many support uploading to S3 buckets using AWS security credentials.

    Using Amazon S3 for forensic artifact collection

    Amazon S3 provides the foundational requirements for collecting and storing forensic artifacts. Digital forensics requires highly available, durable, and secure storage of artifacts collected from potentially compromised systems. Amazon S3 is designed for 11 nines of durability and can be configured to provide protection against modification, deletion, and unauthorized access to sensitive forensic artifacts. You can also use S3 to store forensic artifacts of almost any size—from one byte to 5 TB—in an S3 object.

    S3 buckets used to store forensic artifacts require custom configuration to provide additional security. You should configure the S3 bucket that you use to store forensic artifacts to enable the following security and governance features:

    1. Encryption in transit. You can require the use of encryption in transit and specify acceptable TLS versions using the aws:SecureTransport and s3:TlsVersion condition keys on the S3 bucket policy.
    2. Encryption at rest using a customer managed key. You can automatically encrypt all objects uploaded to the bucket using a specified customer managed key by specifying a default server-side encryption key in the bucket’s configuration. For this post, we encourage you to use a customer managed key rather than relying upon an AWS managed key, so you can control the associated key policy.
      1. Encryption at rest provides an additional layer of protection, because only entities that have both the permission to read from the bucket and permission to use the AWS Key Management Service (AWS KMS) key for decryption can download the forensic artifact from the S3 bucket.
      2. You need to adjust the example KMS policies in this post if the evidence collection S3 bucket uses the S3 Bucket Key feature.
    3. Audit logs of all S3 data event activity. You can turn on CloudTrail data events for any S3 buckets that contain forensic artifacts to provide a comprehensive audit trail of S3 object-level API activity. This helps provide a chain of custody of any artifacts stored in your forensic buckets.
    4. Fine-grained access control using IAM permissions. You can define the set of entities (both human and machine) that have access to the artifacts in the S3 bucket. This post includes how to create time-limited, least privilege access using IAM permissions for uploading files into an S3 bucket. The permissions are fine-grained enough to scope down access to specific object names or object prefixes in an S3 bucket. Additionally, access to read the artifacts can be controlled through IAM permissions and access to the encryption-at-rest KMS key.
    5. Protections against data modification and deletion. S3 provides features, such as S3 object versioning, to provide assurances that data hasn’t been modified or removed after it’s been collected. This is an additional layer of protection beyond the fine-grained access permissions, so even if an authorized entity attempts to overwrite or delete an object in the S3 bucket, the previous version of the object is still available.
    6. There are additional options that you can configure on the S3 bucket to protect your data against modification and deletion, including S3 Object Lock and multi-factor authentication (MFA) delete.

    In addition to the preceding configuration, consider how to organize forensic artifacts in the S3 bucket. This post introduces a folder structure using S3 object prefixes to segregate each forensic artifact collection task into its own S3 object namespace. An example S3 namespace structure for an S3 bucket is shown in Figure 1.

    Figure 1 – S3 namespace structure for an S3 forensics artifact bucket using object prefixes

    Figure 1: S3 namespace structure for an S3 forensics artifact bucket using object prefixes

    By separating each forensic collection task by its own prefix, you can use fine-grained IAM permissions to permit object uploads only into the active collection task. For example, scoped down credentials can be generated to only allow uploads into buckets with the CASE-0001 prefix using an IAM permission as shown in the following code example. Temporary security credentials can be generated using these limited permissions and the key is then used by the forensic acquisition tool to upload the artifacts into the S3 bucket.

    {
    	"Sid": "UploadToCase0001",
    	"Effect": "Allow",
    	"Action": [
    		"s3:PutObject",
    		"s3:AbortMultipartUpload"
    	],
    "	Resource": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"
    }

    Manually creating temporary IAM credentials for each forensic collection activity can be error-prone and time-consuming. Therefore, this post demonstrates how to use AWS tooling to automate the process of generating time-limited, scoped-down credentials.

    Adapt existing forensic tools for AWS best security practices

    Existing forensic tools typically use IAM access keys to perform S3 operations. Using a static IAM user secret access key isn’t a best practice. Even if the static key is associated with an IAM user that has been scoped down to only have access to the forensic collection S3 bucket as described previously, that means anyone with access to that key can potentially upload objects into that bucket. Therefore, the best practice is to create a time-limited temporary security credential unique to each collection activity, scoped down to only allow uploading files to a specific prefix in the target S3 bucket.

    The examples in this post use the following resource names. Because these names will change based on your deployment, substitute your resource names in place of the names in the example code.

    1. The evidence S3 bucket is named mycompany-forensics-collection
    2. The forensics AWS account number is 112233445566. For the purposes of this example, all resources will live within this account.
    3. The customer managed key used to encrypt the forensic artifacts at rest is ForensicsEvidenceKey
    4. The IAM role that incident responders will assume when signing in to their AWS account is ForensicsUserRole
    5. The IAM role that incident responders will use for generating S3 file upload temporary credentials is ForensicsUploadRole
    6. The example uses the us-east-1 AWS Region

    The following steps show you how to configure the IAM policies associated with the customer managed key ForensicsEvidenceKey and the IAM role ForensicsUploadRole.
    Before you begin, create the evidence S3 bucket configured as described in Using S3 for artifact collection and a customer managed key to encrypt the forensic artifacts at rest. Configure the evidence S3 bucket to use the KMS key by opening the S3 bucket’s properties tab in the Amazon S3 console and setting the new KMS key as the default encryption key for the bucket.

    Next, create an IAM role that incident responders will assume through the AWS STS AssumeRole API to generate the temporary credentials. This role will define the maximum set of permissions allowed to upload artifacts to your evidence S3 bucket. This role, ForensicsUploadRole, created using the following example code, defines the maximum allowable permissions: the ability to upload objects into the evidence S3 bucket and to use the KMS key to encrypt those uploads. The effective permissions available to the forensic tool will be scoped down even further to the specific object prefix when the AWS STS temporary security credential is generated.

    Note that the policy allows the forensics upload role Decrypt permission in addition to Encrypt; this is required when uploading files larger than 5 GB using the multi-part S3 file upload feature.

    {
    	"Version": "2012-10-17",
    	"Statement": [
    			{
    				"Sid": "BasePermissionsForS3Upload",
    				"Effect": "Allow",
    				"Action": [
    					"s3:PutObject",
    					"s3:AbortMultipartUpload"
    				],
    				"Resource": "arn:aws:s3:::mycompany-forensics-collection/*"
    		},
    		{
    			"Sid": "KeyAccessToS3Upload",
    			"Effect": "Allow",
    			"Action": [
    				"kms:GenerateDataKey",
    				"kms:Encrypt",
    				"kms:Decrypt"
    			],
    			"Resource": "arn:aws:kms:us-east-1:112233445566:alias/ForensicsEvidenceKey",
    			"Condition": {
    				"StringLike": {
    					"kms:EncryptionContext:aws:s3:arn": "arn:aws:s3:::mycompany-forensics-collection/*"
    				}
    			}
    		}
    	]
    }

    Next, you need to provide an ability to assume this role and generate AWS STS tokens using the role’s permissions. This is accomplished by creating a trust relationship associated with the IAM role you just created. The trust relationship shown in the following code sample describes which AWS principals are allowed to assume the role—in this case, you will allow any user who has federated into the ForensicsUserRole IAM role to be able to generate AWS STS tokens for forensic artifact collection.

    {
    	"Version": "2012-10-17",
    	"Statement": [
    		{
    			"Sid": "Statement1",
    			"Effect": "Allow",
    			"Principal": {
    				"AWS": "arn:aws:iam::112233445566:role/ForensicsUserRole"
    			},
    			"Action": "sts:AssumeRole"
    		}
    	]
    }

    After the role is established and access to the encryption key is granted, you can use the AWS STS AssumeRole API to create temporary credentials using this role. You can call this API using the AWS Command Line Interface (AWS CLI) or programmatically from a script. To scope down the token’s access to only provide permission to upload to the specific evidence object prefix, you must include a session policy as part of your AssumeRole API request to AWS STS. The following is an example session policy to restrict access to only upload objects into the CASE-0001 prefix.

    [
    	{
    		"Effect": "Allow",
    		"Action": [
    			"s3:PutObject", 
    			"s3:AbortMultipartUpload"
    		],
    		"Resource": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"
    	},
    	{
    		"Effect": "Allow",
    		"Action": [
    			"kms:GenerateDataKey", 
    			"kms:Encrypt", 
    			"kms:Decrypt"
    		],
    		"Resource": "*",
    		"Condition": {
    			"StringLike": {
    				"kms:EncryptionContext:aws:s3:arn": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"
    			}
    		}
    	}
    ]

    The effective permissions available to the session role will be the intersection of permissions available in the role policy (ForensicsUploadRole), the resource policy (in this case, mandating TLS-encrypted connections to the bucket), and the session policy that’s created on demand for every forensic collection (only allowing access to upload objects into the CASE-0001 prefix, as shown in the preceding example). Pictorially, this looks like the Venn diagram shown in Figure 2.

    Figure 2 – Intersection of IAM policies determine the effective permissions for the restricted forensic session role.

    Figure 2: Intersection of IAM policies determine the effective permissions for the restricted forensic session role.

    Test the temporary credentials

    Now that the bucket has been created and the AWS KMS key and roles configured, you can use AWS STS to create a temporary security credential for a collection on CASE-0001. You can use the AWS CLI to do this manually or you can write a script to automate this process using the AWS API. The IAM access key, secret access key, and session token returned by this call can then be used by any tool that can use AWS access keys to upload files into the specified S3 bucket.

    The following example shows an AWS CLI call to AssumeRole using the example ForensicsUploadRole and a case named CASE-0001. The --duration-seconds parameter defines the period, in seconds, that the temporary credentials are valid; the default of 3600 seconds will provide temporary credentials that are valid for one hour.

    $ aws sts assume-role \
    	--role-arn arn:aws:iam::112233445566:role/ForensicsUploadRole \
    	--role-session-name CASE-0001 \
    	--duration-seconds 3600 \
    	--policy '{"Version": "2012-10-17", "Statement": [{"Effect": "Allow", "Action": ["s3:PutObject", "s3:AbortMultipartUpload"], "Resource": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"}, {"Sid": "BasePermissionsForS3Upload", "Effect": "Allow", "Action": ["kms:GenerateDataKey", "kms:Encrypt", "kms:Decrypt"], "Resource": "*"}]}'
    
    {
    	"Credentials": {
    		"AccessKeyId": "ASIAXXXX",
    		"SecretAccessKey": "XXXX",
    		"SessionToken": "XXXX",
    		"Expiration": "2025-04-10T17:16:13+00:00"
    	},
    	"AssumedRoleUser": {
    		"AssumedRoleId": "AROXXXX:CASE-0001",
    		"Arn": "arn:aws:sts::112233445566:assumed-role/ForensicsUploadRole/CASE-0001"
    	},
    	"PackedPolicySize": 39
    }

    Now that you have obtained temporary credentials from AWS STS, you can use those credentials to upload a file into Amazon S3:

    $ AWS_ACCESS_KEY_ID=ASIAXXXX \
    	AWS_SECRET_ACCESS_KEY=XXXX \
    	AWS_SESSION_TOKEN=XXXX \
    	aws s3 cp evidence.zip s3://mycompany-forensics-collection/CASE-0001/evidence.zip
    
    upload: evidence.zip to s3://mycompany-forensics-collection/CASE-0001/evidence.zip

    You can also verify that you can’t use those credentials to upload a file into any other object prefixes or S3 buckets. For example, if you change CASE-0001 to CASE-0004 in the Amazon S3 upload command, you will receive an AccessDenied error because you’re trying to upload an object outside of the allowed key prefix.

    $ AWS_ACCESS_KEY_ID=ASIAXXXX \
    	AWS_SECRET_ACCESS_KEY=XXXX \
    	AWS_SESSION_TOKEN=XXXX \
    	aws s3 cp evidence.zip s3://mycompany-forensics-collection/CASE-0004/evidence.zip
    
    upload failed: evidence.zip to s3://mycompany-forensics-collection/cases/CASE-0004/evidence.zip
    An error occurred (AccessDenied) when calling the PutObject operation: User: arn:aws:sts::112233445566:assumed-role/ForensicsUploadRole/CASE-0001 is not authorized to perform: s3:PutObject on resource: "arn:aws:s3:::mycompany-forensics-collection/CASE-0004/evidence.zip" because no session policy allows the s3:PutObject action

    Additionally, if you wait more than the lifetime of the token (1 hour in this case), attempting to upload a file into the bucket will fail, because the token will no longer be valid:

    $ AWS_ACCESS_KEY_ID=ASIAXXXX \
    	AWS_SECRET_ACCESS_KEY=XXXX \
    	AWS_SESSION_TOKEN=XXXX \
    	aws s3 cp evidence.zip s3://mycompany-forensics-collection/CASE-0001/evidence.zip
    
    upload failed: evidence.zip to s3://mycompany-forensics-collection/CASE-0001/evidence.zip
    
    An error occurred (ExpiredToken) when calling the PutObject operation: The provided token has expired.

    Create an automated process to vend temporary credentials on demand

    After you’ve verified the security benefits of creating temporary credentials for S3 uploads and validated that the credentials work with your forensic software of choice, you can now use them as part of an automated process.

    A sample automated architecture is shown in Figure 3.

    Figure 3: Architecture to automate S3 credential vending and forensic artifact collection.

    Figure 3: Architecture to automate S3 credential vending and forensic artifact collection.

    The workflow depicted in Figure 3 includes the following steps:

    1. The workflow is triggered by an alert from a detection source or a manual trigger from an incident responder.
    2. The workflow input is added to an Amazon Simple Queue Service (Amazon SQS) queue.
    3. The Amazon SQS queue invokes an AWS Lambda function which in turn executes a Step Functions state machine to orchestrate the workflow.
    4. First, the Step Functions workflow determines whether the target system is managed by AWS Systems Manager.
      1. If the target system isn’t managed by Systems Manager, an error is noted, and the execution is abandoned.
      2. If the target system is managed by Systems Manager, the Step Functions workflow determines the operating system (OS) of the target system and proceeds with the flow of execution.
    5. The workflow then continues by executing the Systems Manager documents that implement the forensic collection process:
      1. Downloads tooling:
        1. Generates dynamically scoped IAM temporary credentials that provide access to download the OS-specific tooling to be executed on the target system from the tooling S3 bucket. These credentials are tightly scoped to only allow downloads from the S3 prefix that corresponds to the tooling for the target system’s OS.
        2. Executes a Systems Manager command on the target system that uses the credentials generated from the previous step to download the OS tooling on the target system.
      2. Runs forensic tools:
        • Executes a Systems Manager command on the target system to execute the OS tooling on the target system.
    6. The Systems Manager commands run on the target system, which in this case is an EC2 instance.
    7. Results are uploaded to the evidence S3 bucket:
      1. Generates dynamically scoped IAM temporary credentials (as described previously) that provide access to upload the output of the previously executed tooling to the evidence S3 bucket. These credentials are tightly scoped to only allow uploads to a particular S3 prefix corresponding to the alert prefix.
      2. Executes a Systems Manager command on the target system to upload the output of the previously executed tooling to the evidence S3 bucket. After the upload is complete, it cleans up both the output and the evidence tooling from the target system.
      3. The evidence S3 bucket is tightly locked down to a subset of identities within the AWS security account. Access attempts from identities that aren’t allow listed trigger an Amazon EventBridge rule to alert the security team through an Amazon Simple Notification Service (Amazon SNS) topic.
    8. When the workflow is complete, related details and metrics are recorded in an Amazon DynamoDB table.
    9. The forensic analysis can be performed on a separate EC2 instance that has access to read from the evidence S3 bucket.

    Deploying the example solution

    You can use the AWS Cloud Development Kit (AWS CDK) repository to implement the architecture shown in Figure 3.

    The AWS CDK solution is split into three stacks:

    1. SecurityStack: This stack contains the basic forensic artifact workflow orchestration infrastructure described in this post, including the Step Functions workflow, Lambda functions, AWS SQS queues, IAM roles, and S3 buckets.
    2. AlertStack: This stack contains the EventBridge workflow to notify administrators of anomalous activity in the evidence S3 bucket.
    3. CustomerStack: This stack contains the SSM documents that are executed for the forensic artifact workflow and an IAM role assumed by the SecurityStack when the workflow is invoked. It’s deployed into each child AWS account containing EC2 instances from which the security account is authorized to collect forensic artifacts.

    Configuration

    Before deploying the solution, there are several variables in the config.ts file that must be modified for the environment:

    1. SECURITY_ACCOUNT: Security Tooling AWS account ID.
    2. CUSTOMER_ACCOUNTS: Target AWS account IDs (the Child AWS account in the architecture diagram).
    3. ALERT_EMAIL_RECIPIENTS: List of email addresses that receive alerts when there is unexpected access to the evidence S3 bucket.
    4. ALLOW_LISTED_ROLE_NAMES: Roles allowed to access the evidence S3 bucket. Any other identities accessing the evidence S3 bucket will result in an alarm.

    Deployment

    After you’ve updated the config.ts file to reflect the account numbers, email recipients, and role names, the stacks can be deployed into your AWS infrastructure.

    1. Set Up AWS credentials using the AWS CLI:
      aws configure
    2. Install dependencies and configure constants:
      1. Clone the repository.
      2. Navigate to the project directory.
      3. Install project dependencies:
        npm install
      4. Configure constants in constants/config.ts with the required information:
        export const SECURITY_ACCOUNT = "123456789012"; // Your security tooling account ID 
        export const CUSTOMER_ACCOUNTS = ["234567890123", "345678901234"]; // Target account IDs 
        export const ALLOW_LISTED_ROLE_NAMES = ["SecurityAnalystRole"];// Roles allowed to access evidence S3 bucket 
        export const ALERT_EMAIL_RECIPIENTS = ["[email protected]"];// Email addresses for alerts

    3. Bootstrap AWS CDK in your accounts (if it hasn’t been done already):
      1. Example: cdk bootstrap aws://456789012345/us-east-1 (example security AWS account).
      2. Then bootstrap if necessary in any target AWS accounts.
    4. Deploy the AWS CDK Stacks:
      1. Synthesize the CloudFormation template:
        cdk synth
      2. Deploy the security and alert stacks in your security account:
        cdk deploy SecurityStack AlertStack
      3. Deploy the customer stacks in your workload accounts:
        cdk deploy CustomerStack-ACCOUNT_ID
    5. Set up your email alerts:
      1. After the AlertStack is deployed, it will email all addresses listed in ALERT_EMAIL_RECIPIENTS. Choose the embedded link to accept the AWS SNS topic in each of those accounts.

    Testing

    With deployment complete, it’s time to test the solution.

    1. Trigger an analysis
      1. Make sure you have a Linux EC2 instance running in one of your customer accounts and in the AWS Region where you deployed the preceding customer stack.
      2. Because this example uses Systems Manager to orchestrate the collection script, make sure that the EC2 instance is visible in Systems Manager either by checking the Systems Manager console, or by using the AWS CLI:
        1. Console: In the AWS Systems Manager console, choose Managed instances in the left navigation pane and verify your instance appears in the list. For more information, see Managed Instances in the AWS Systems Manager User Guide.
        2. AWS CLI: Run the following command to verify the instance is managed:
          aws ssm describe-instance-information --filters “Key=InstanceIds,Values=<instance-id>
          If the command returns instance information with PingStatus: Online, the instance is properly connected to Systems Manager.
      3. Post a message in your security account to the Amazon SQS queue to start the Step Functions workflow. Note that the values in angle brackets (for example <accountID>) are placeholders that you must update with relevant AWS account ID, tracking ticket ID, AWS Region, and EC2 instance ID values:
        aws sqs send-message --queue-url --message-body ‘{ “account”: “”, “ticket_id”: “”, “region”: “>”, “instance_id”: “” }’
    2. Go to the Step Functions console to view the successful execution of the workflow:
      Figure 4 – Workflow as shown in the Step Functions console

      Figure 4: Workflow as shown in the Step Functions console

    3. View the DynamoDB table to see the metadata for the results.
    4. Check the evidence S3 bucket to see the uploaded files from the forensic collection.

    Conclusion

    Collecting forensic artifacts securely is a critical component of any digital forensics investigation. This post demonstrated how to implement least privilege access controls and time-limited credentials for forensic evidence collection workflows that use Amazon S3 for artifact storage. By combining IAM session policies with AWS STS temporary credentials, you can provide forensic tools with secure, scoped-down access to upload artifacts without exposing long-lived credentials or granting overly permissive access.

    The architecture presented in this post automates the process of generating temporary credentials, collecting forensic artifacts from both AWS and non-AWS resources, and securely storing them in S3 buckets with appropriate encryption, access controls, and audit logging. With this approach, your security teams can focus on analyzing evidence instead of managing credentials and permissions during active security incidents.To get started with this solution, deploy the example AWS CDK stacks provided in the collect forensic artifacts repository and customize them for your organization’s forensic investigation requirements. For more information about related AWS forensic investigation architectures, review the Automated Forensics Orchestrator for EC2 and How to build forensic kernel modules for Linux EC2 instances resources.

    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

    Jason Garman

    Jason Garman

    Jason is a principal security specialist solutions architect at AWS. He has 30 years of cybersecurity experience including incident response, reverse engineering, identity, and data protection. At AWS, he helps large organizations adopt the latest cloud and AI technologies while maintaining a high bar for data governance, security, and safety.

    Vaishnav Murthy

    Vaishnav Murthy

    Vaishnav is a Senior Security Engineer with AWS CloudResponse. He has an extensive background in incident response and security automation and enjoys building automated solutions that help AWS customers investigate and respond to security incidents at scale.

    Streamline Apache Kafka topic management with Amazon MSK

    Post Syndicated from Swapna Bandla original https://aws.amazon.com/blogs/big-data/streamline-apache-kafka-topic-management-with-amazon-msk/

    If you manage Apache Kafka today, you know the effort required to manage topics. Whether you use infrastructure as code (IaC) solutions or perform operations with admin clients, setting up topic management takes valuable time that could be spent on building streaming applications.

    Amazon Managed Streaming for Apache Kafka (Amazon MSK) now streamlines topic management by supporting new topic APIs and console integration. You can programmatically create, update, and delete Apache Kafka topics using familiar interfaces including AWS Command Line Interface (AWS CLI), AWS SDKs, and AWS CloudFormation. With these APIs, you can define topic properties such as replication factor and partition count and configuration settings like retention and cleanup policies. The Amazon MSK console integrates these APIs, bringing all topic operations to one place. You can now create or update topics with a few selections using guided defaults while gaining comprehensive visibility into topic configurations, partition-level information, and metrics. You can browse for topics within a cluster, review replication settings and partition counts, and go into individual topics to examine detailed configuration, partition-level information, and metrics. A unified dashboard consolidates partition topics and metrics in one view.

    In this post, we show you how to use the new topic management capabilities of Amazon MSK to streamline your Apache Kafka operations. We demonstrate how to manage topics through the console, control access with AWS Identity and Access Management (IAM), and bring topic provisioning into your continuous integration and continuous delivery (CI/CD) pipelines.

    Prerequisites

    To get started with topic management, you need:

    • An active AWS account with appropriate IAM permissions for Amazon MSK.
    • An existing Amazon MSK Express or Standard cluster using Apache Kafka version 3.6 and above.
    • Basic familiarity with Apache Kafka concepts like topics, partitions, and replication.
    • AWS CLI installed and configured (for command line examples).

    Creating topics

    The MSK console provides a guided experience with sensible defaults while still offering advanced configuration options when you need them.

    1. Navigate to the Amazon MSK console and select your cluster.
    2. Choose the Topics tab, then choose Create topic.
    3. Enter a topic name (for example, customer-orders).
    4. Specify the number of partitions (use the guided defaults or customize based on your needs).
    5. Set the replication factor. Note that Express brokers improve the availability and durability of your Amazon MSK clusters by setting values for critical configurations and protecting them from common misconfiguration. If you try to create a topic with a replication factor value other than 3, Amazon MSK Express will create the topic with a replication factor of 3 by default.
    6. (Optional) Configure advanced settings like retention period or message size limits.
    7. Choose Create topic.

    The console validates your configuration and creates the topic. You can create multiple topics simultaneously with the same configuration settings. These topic API responses reflect data that updates approximately every minute. For the most current topic state after making changes, wait approximately one minute before querying.

    Configuration considerations

    When choosing configuration options, consider your workload requirements:

    Viewing and monitoring topics

    After you create topics, the MSK console provides comprehensive visibility into their configuration. When you select a specific topic, you will see detailed information:

    • Partitions tab: Shows the distribution of partitions across brokers, including leader assignments and in-sync replica status showcasing Broker IDs for leader and replicas.
    • Configuration tab: Displays all topic-level configuration settings.
    • Monitoring tab: Integrates with Amazon CloudWatch to show metrics like bytes in/out, message rates, and consumer lag.

    Updating topic configurations

    As your workload requirements evolve, you might need to adjust topic configurations. You can modify various topic settings depending on your cluster type. For example:

    • Retention settings: Adjust retention.ms (time-based) or retention.bytes (size-based) to control how long messages are retained.
    • Message size limits: Modify max.message.bytes to accommodate larger or smaller messages.
    • Compression: Change compression.type to optimize storage and network usage.

    Configuration changes take effect immediately for new messages. Existing messages remain subject to the previous configuration until they age out or are consumed.

    Deleting topics

    Amazon MSK also provides APIs for deleting topics that are no longer in use. Before deleting a topic, verify that:

    • No active producers are writing to the topic
    • All consumers have finished processing messages
    • You have backups if you need to retain the data
    • Downstream applications won’t be impacted

    Important: Topic deletion permanently removes all messages in the topic.

    Control access with IAM

    Beyond streamlining topic operations, you also need appropriate access controls. Access control uses IAM, so you define permissions using the same model that you apply to other AWS resources. Amazon MSK uses a two-level permission model:

    • Resource-level permissions: An IAM policy that enforces which operations the cluster will allow
    • Principal-level permissions: IAM policies attached to Roles or Users that enforce which operations a principal is allowed to perform on a cluster

    With this separation, you can control access depending on your organizational needs and access patterns for your cluster. Refer to the IAM permissions documentation for IAM permissions required for topic management for the Amazon MSK cluster.

    You can grant your operations team broad access to manage all topics and restrict application teams to manage only their own topics. The permission granularity that you need is available through standard IAM policies. If you’ve already configured IAM permissions for Apache Kafka topics, they work immediately with the new functionality without any migration or reconfiguration.

    Here is a sample IAM policy definition that allows Describe Topic API

    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "kafka-cluster:Connect"
                ],
                "Resource": [
                    "arn:aws:kafka:us-east-1:111111111111:cluster/iam-auth-acl-test/a6b5c6d5-f74f-4dbc-ad14-63fb5e87fe4f-2"
                ]
            },
            {
                "Effect": "Allow",
                "Action": [
                    "kafka-cluster:DescribeTopic",
                    "kafka-cluster:DescribeTopicDynamicConfiguration"
                ],
                "Resource": [
                    "arn:aws:kafka:us-east-1:111111111111:topic/iam-auth-acl-test/a6b5c6d5-f74f-4dbc-ad14-63fb5e87fe4f-2/*"
                ]
            }
        ]
    }

    This IAM policy grants the necessary permissions to describe Kafka topics in your Amazon MSK cluster. The policy includes three key permissions:

    • kafka-cluster:Connect – Allows connection to the specified MSK cluster
    • kafka-cluster:DescribeTopic – Enables viewing topic details
    • kafka-cluster:DescribeTopicDynamicConfiguration – Enables viewing topic dynamic configuration

    The policy is scoped to a specific cluster ARN and applies to all topics within that cluster using the wildcard pattern /*. Replace the placeholder Amazon MSK cluster ARN with your MSK cluster ARN.

    Infrastructure as Code

    If you manage infrastructure as code (IaC), you can now define topics alongside clusters in your CloudFormation templates:

    Resources:
        OrdersTopic:
          Type: AWS::MSK::Topic
          Properties:
            ClusterArn: !GetAtt MyMSKCluster.Arn
            TopicName: orders
            NumPartitions: 6
            ReplicationFactor: 3
            Config:
              retention.ms: "604800000"

    This approach brings topic provisioning into your CI/CD pipelines.

    Availability and pricing

    The new Amazon MSK topic management experience is available today for Standard and Express Amazon MSK clusters using Apache Kafka version 3.6 and above in all AWS Regions where Amazon MSK is offered, at no additional cost.

    Cleanup

    To avoid incurring additional charges to your AWS account, ensure you delete all resources created during this tutorial, including:

    • Amazon MSK cluster
    • Any Kafka topics created
    • Associated AWS resources (security groups, VPCs, etc., if created specifically for this blog)

    Remember to verify that all resources have been successfully removed to prevent ongoing costs.

    Conclusion

    Topic management has been a persistent pain point for Apache Kafka operations. The new integrated experience in Amazon MSK now reduces operational friction by bringing topic operations into the AWS tools that you use every day. You now have a consistent, streamlined way to handle these operations for all Apache Kafka topics across multiple MSK clusters. This capability reflects our commitment to reducing operational complexity in Apache Kafka. You get the reliability and performance of Apache Kafka without the operational overhead that traditionally comes with it. Your team spends less time on infrastructure maintenance and more time building streaming applications that drive your business forward.

    Ready to start streamlining your topic management? Start managing your topics today through the Amazon MSK console or by visiting the Amazon MSK documentation.


    About the authors

    Swapna Bandla

    Swapna is a Senior Streaming Solutions Architect at AWS. With a deep understanding of real-time data processing and analytics, she partners with customers to architect scalable, cloud-native solutions that align with AWS Well-Architected best practices. Swapna is passionate about helping organizations unlock the full potential of their data to drive business value. Beyond her professional pursuits, she cherishes quality time with her family.

    Mazrim Mehrtens

    Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. They work with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

    Judy Huang

    Judy is a Senior Product Manager for Amazon Managed Streaming for Apache Kafka (MSK) at AWS. She is passionate about real-time data systems and helping organizations unlock the value of streaming data at scale. Her work focuses on improving how customers manage Kafka infrastructure and building capabilities that make streaming platforms more accessible, resilient, and integrated with the broader data ecosystem.

    Navigating multi-account deployments in Amazon SageMaker Unified Studio: a governance-first approach

    Post Syndicated from Ben Shafabakhsh original https://aws.amazon.com/blogs/big-data/navigating-multi-account-deployments-in-amazon-sagemaker-unified-studio-a-governance-first-approach/

    Amazon SageMaker Unified Studio brings together data engineering, analytics, and machine learning (ML) workflows into a cohesive, governed environment. This unified approach reduces traditional silos between data teams and ML practitioners, so organizations can advance their AI and ML initiatives with greater collaboration and efficiency.

    As enterprises begin their SageMaker Unified Studio adoption, they must determine the best practices for implementing data federation principles when using SageMaker Unified Studio across the organization. The way that you structure your SageMaker Unified Studio deployment is more than a technical decision. It directly impacts your governance framework, security posture, operational scalability, and day-to-day team collaboration.

    In this post, we explore SageMaker Unified Studio multi-account deployments in depth: what they entail, why they matter, and how to implement them effectively. We examine architecture patterns, evaluate trade-offs across security boundaries, operational overhead, and team autonomy. We also provide practical guidance to help you design a deployment that balances centralized control with distributed ownership across your organization.

    The multi-account challenge: why organizations struggle

    If you’re working in a large enterprise, a multi-account AWS environment is often your starting position. If you’re starting from scratch, consider whether to use a single-account for all SageMaker Unified Studio components or dedicate separate accounts for governance and business units. A multi-account architecture aligns with AWS best practices and proves valuable if you have:

    • Distributed teams with independent operations: multi-account architecture accommodates multiple teams or business units that maintain separate operations so that each team can manage their projects autonomously within isolated environments. Each unit can deploy and manage resources independently, implement team-specific security controls, and scale infrastructure without impacting others. This is achieved through a shared, unified integrated development environment (IDE) for collaboration and standardized tools across the organization.
    • Compliance and data governance requirements: For regulatory mandates like GDPR, HIPAA, or data sovereignty needs, you will benefit from this setup, because sensitive data remains segregated in business-unit specific accounts. This reduces risk exposure, streamlines audits, and maintains compliance boundaries without compromising access to centralized collaboration tools.
    • Centralized governance: A multi-account architecture maintains visibility across all projects and business units from a single control plane. The Domain account can enforce security policies and compliance requirements across the entire organization and provide centralized monitoring, audit logging, and user access management.
    • Clear cost visibility and accountability: Multi-account architecture enables granular billing tracking, with each account generating separate bills that clearly attribute costs to specific teams or business units. This transparency streamlines budgeting and financial accountability, removing the complexity of cost allocation tags and manual reporting that’s typically required in single-account models where multiple teams share the same infrastructure and resources.

    Overall, this approach improves efficiency, security, and scalability for you, whether you’re managing a few teams or coordinating across a larger organizational structure.

    Understanding the core constructs of SageMaker Unified Studio

    Before diving into multi-account strategies, it’s important to understand the foundational constructs of SageMaker Unified Studio. Each is elaborated in greater detail in the Administrator Guide.

    • Domain: The top-level administrative boundary where governance lives. In a multi-account setup, this is your centralized control plane for catalog, policies, and user access.
    • Project: A collaborative workspace for developing data, AI, and ML initiatives. In multi-account deployments, a Project’s metadata lives in the Domain account and compute and data resources deploy into associated business unit accounts. This separation is central to the pattern that we explore.
    • Project Profile: A template that standardizes how Projects are created. For multi-account setups, this is where administrators define which accounts and AWS Regions Projects can target.
    • Blueprints: Infrastructure as code (IaC) components that define what gets provisioned inside a Project. Each associated account must enable its relevant Blueprints before Projects can deploy there.

    The following diagram illustrates how these key constructs interact. Within a Domain, users create Projects organized through a single Project Profile. The Project Profile defines and configures a collection of Blueprints. When a project is created, the infrastructure specified in those Blueprints is automatically provisioned and becomes available within the project workspace.

    SageMaker Unified Studio Domain architecture diagram demonstrating blueprint management and infrastructure deployment workflow. This technical diagram illustrates how AWS SageMaker projects utilize enabled blueprints through profile configuration to deploy infrastructure resources. The workflow shows Project ABC with People, Data/Code, and Compute/Resources components connecting to Project Profile X, which filters enabled blueprints (Tooling Blueprint and X Blueprint) for deployment while excluding disabled blueprints (Y Blueprint and Z Blueprint). The deployed infrastructure section displays the resulting Tooling Blueprint Infrastructure and X Blueprint Infrastructure as purple cube icons, representing the final deployed resources in the SageMaker environment.
    Figure 1: Amazon SageMaker Unified Studio Core Constructs

    Multi-account setup in SageMaker Unified Studio

    To illustrate these concepts in practice, we demonstrate with a sample enterprise organization that exemplifies enterprise environments with several AWS accounts belonging to different business units:

    • Central Data Governance team: Owns and manages governance and access control across the organization. They plan to build a data solution in a dedicated AWS account using SageMaker Unified Studio. The platform must provide an integrated development environment (IDE) to work with data and ML use cases and connect to multiple business unit’s AWS accounts (Finance and Marketing).
    • Finance Business Unit: Owns datasets for fraud analysis and churn prediction in their own AWS account.
    • Marketing Business Unit: Maintains customer sentiment data and campaign analytics in their own AWS account.

    In the following diagram we show the Data platform constructs provided by SageMaker Unified Studio in each AWS account showing the clear separation between centralized governance and distributed resource deployment.

    AWS multi-account data governance architecture diagram illustrating centralized policy management with distributed departmental execution. This enterprise architecture shows how a Central Data Governance Team maintains standards across multiple AWS accounts. The Central Data Governance Account serves as the control plane, housing the Domain with Platform Resources (Catalog and Shared infrastructure), Governance Constructs (Domain Units and Metadata Forms), and Governance Policies (Authorization Policies and Enforcement). Marketing Teams and Finance Teams access their respective projects within the central governance framework, which then connect to separate Marketing and Finance AWS accounts. Each departmental account maintains its own Resources and Data infrastructure while adhering to centralized governance standards, enabling federated data management with consistent oversight across the organization.

    Figure 2: Sample organization architecture in Amazon SageMaker Unified Studio

    The Central Data Governance Account contains the SageMaker Unified Studio Domain. This contains the shared platform resources (Catalog, shared infrastructure), governance constructs (Domain units, metadata forms), and governance policies (authorization policies, enforcement rules). These configuration elements define the standards and capabilities available across the organization. They’re the Service-level configuration data: Metadata, policies, and governance rules that define how resources should be provisioned.

    In contrast, the Associated Accounts (Marketing and Finance) contain the actual AWS infrastructure, compute/storage (purple cubes) and data stores (cylinders), provisioned when Projects are created. The diagram shows how Marketing Projects and Finance Projects ultimately deploy their runtime resources into their respective business unit accounts. The separation keeps the governance centralized and consistent while allowing business unit dependent resources to be isolated, billed separately, and managed according to each business unit’s specific requirements.

    To understand the core constructs of SageMaker Unified Studio, we listed the core components of SageMaker Unified Studio and explained how they relate to each other. Taking the same diagram as the basis, we will now represent how these constructs are created in our multi-account sample scenario.

    Construct Deployment Location Deployed Resources
    Domain Central Data Governance Account
    • Portal
    • Catalog
    • Metadata Forms
    • Authorization Policies
    Project Central Data Governance Account + Associated Account In Central Data Governance Account:

    • Project configuration and metadata

    In Associated Account:

    • Project Infrastructure resources such as Compute
    • Project Data
    Project Profile Central Data Governance Account
    • Project Profile Configuration
    Blueprint Associated Account
    • Blueprints are enabled in each associated account

    Core construct deployment locations and resources in SageMaker Unified Studio

    Implementing multi-account deployments

    To enable production-ready data science and analytics workflows across multiple AWS accounts governed by a SageMaker Unified Studio Domain, organizations must establish a structured cross-account configuration. This setup allows each business unit (BU) to retain ownership of its Projects and AWS resources while using centralized governance provided by the Domain. The process involves four key steps: account association, Blueprint enablement, Project Profile configuration, and Project creation.

    Note: The following steps provide a high-level overview of the multi-account deployment process. For a more detailed, step-by-step guide, refer to How to associate an account when using Amazon SageMaker Unified Studio.

    Step 1: Account association to a domain

    The Domain administrator associates each AWS account with the SageMaker Unified Studio Domain for seamless cross-account functionality by providing the AWS account number for the targeted accounts. This association lets the Domain publish and consume data from associated accounts, create resources within them, maintain cross-account access for the SageMaker Catalog, and deploy Projects directly into business unit accounts. Account association is a critical prerequisite for cross-account Project deployment. Behind the scenes, SageMaker Unified Studio uses AWS Resource Access Manager (AWS RAM) to make this cross-account functionality happen.

    Step 2: Enabling blueprints

    Each associate account administrator must enable the relevant Blueprints before creating Project Profiles. This important step verifies that Projects can provision the necessary tools and resources that users need to run their workloads. Blueprints serve as standardized infrastructure templates that administrators can use to enforce organizational standards, security controls, and best practices across all Projects. Through Blueprints, administrators configure essential resources including AWS Identity and Access Management (IAM) roles, AWS Key Management Service (AWS KMS) keys, Amazon Simple Storage Service (Amazon S3) buckets, Amazon Virtual Private Cloud (Amazon VPC) settings, and security groups. This centralized approach helps maintain consistency, compliance, and governance at scale while preventing users from creating Projects with misconfigured or non-compliant infrastructure.

    Step 3: Configuring project profile

    With the accounts successfully associated and the Blueprints enabled, the next step is to configure a Project Profile that determines where your Project resources will be deployed. Your choice of Project Profile strategy impacts both operational flexibility and governance.

    Domain administrators control which Blueprints are included in each Project Profile and can specify the target AWS Regions and accounts for deployment, providing the governance foundation to standardize Project creation. Administrators can use pre-created Project Profiles like “All Capabilities” or “SQL Analytics”, or create custom Project Profiles tailored to specific organizational needs.

    When configuring Project Profiles, you can choose between two deployment models:

    • Static (Pre-Defined): Profile specifies a fixed account and Region. Projects by default deploy to the same location. This is recommended for strict governance controls and compliance requirements where production resources must remain in designated accounts or Regions.
    • Dynamic (Parameterized): Users select from available associated accounts and Regions during Project creation (configured through Account Pools). This is recommended for multi-environment workflows (Dev/Test/Prod) and reducing administrative overhead by maintaining fewer profile templates.

    Dynamic profiles balance governance with agility: Administrators define standards once, while users retain deployment flexibility aligned with their business needs.

    Step 4: Project creation

    With Project Profiles configured, you can now create a new Project from any of the associated accounts using the profile created in the previous step.

    Defining project boundaries: when to create a new project

    One of the common challenges that you will face is determining when to create a new Project. The answer significantly impacts collaboration effectiveness, resource isolation, cost tracking, and governance. Here’s a practical framework to guide your decision-making.

    A Project should represent a distinct business initiative with a defined scope, a dedicated team, and measurable outcomes. Think of Projects as team workspaces organized around business outcomes, not technical components.

    Create a new Project when you need clear separation across multiple dimensions: cost allocation, access control, and data governance. If Finance and Marketing teams require separate budget tracking, distinct data access policies, and different governance controls, they should have separate Projects. For example, “Customer Churn Prediction” and “Fraud Detection” might use similar tools, but if they have different stakeholders, budget owners, and data sensitivity requirements, so they warrant separation. Similarly, create separate Projects when facing different compliance or regulatory requirements (like HIPAA versus PCI-DSS) or when initiatives have independent deployment lifecycles. Experimental ML research Projects shouldn’t share workspaces with production recommendation engines that require stricter change controls and availability guarantees.

    However, avoid fragmenting related work into unnecessary silos:

    • Don’t create separate Projects for individual workflows or pipelines, a single “Marketing Campaign Optimization” Project should contain audience segmentation, propensity modeling, and campaign attribution workflows together.
    • Don’t separate different data processing stages; keep data ingestion, transformation, and analysis within one Project to maintain clear lineage and enable seamless collaboration.
    • Projects are team workspaces, not personal sandboxes, so use shared Projects with role-based access control rather than creating individual Projects per team member.
    • Small proof of concepts (POC) or temporary experiments should be conducted within the parent Project, with successful initiatives promoted to dedicated production Projects only when they mature into full-scale capabilities requiring independent governance.

    Conclusion

    Throughout this post, we explored how the separation of governance and working accounts forms the foundation of a scalable, secure, and compliant data and AI platform.

    With centralized governance in the Domain account, organizations can enforce consistent security policies, compliance requirements, and cost management, while allowing sub-accounts the autonomy over their own resources. This approach enhances security and compliance, and fosters collaboration and innovation within teams by providing them with the flexibility that they need to operate effectively. Ultimately, this governance-first strategy supports keeping data remains protected and accessible in a controlled manner, empowering teams to drive business outcomes efficiently. To implement a multi-account deployment for your organization, get started by creating your first SageMaker Unified Studio Domain and follow the step-by-step guidance to establish your governance-first architecture.


    About the authors

    Ben Shafabakhsh

    Ben Shafabakhsh

    Ben is a Partner Solution Architect at AWS. He works with AWS consulting and system integrator partners in building technology solutions and implementing strategies to drive adoption of AWS services.

    Adriana Lopez

    Adriana Lopez

    Adriana is a Software Development Engineer at AWS Professional Services. She is passionate about data and AI governance, focusing on building ingenious solutions that empower teams with the data and AI agents and tools they need to innovate.

    Juan Daza

    Juan Daza

    Juan is a Senior Delivery Consultant for Data & Analytics at AWS Professional Services. He specializes in the design, development, and deployment of modern data and analytics platforms. His work focuses on data governance and architecting AI-ready data systems.