Post Syndicated from Anderson dos Santos original https://aws.amazon.com/blogs/big-data/get-started-managing-partitions-for-amazon-s3-tables-backed-by-the-aws-glue-data-catalog/
Large organizations processing huge volumes of data usually store it in Amazon Simple Storage Service (Amazon S3) and query the data to make data-driven business decisions using distributed analytics engines such as Amazon Athena. If you simply run queries without considering the optimal data layout on Amazon S3, it results in a high volume of data scanned, long-running queries, and increased cost.
Partitioning is a common technique to lay out your data optimally for distributed analytics engines. By partitioning your data, you can restrict the amount of data scanned by downstream analytics engines, thereby improving performance and reducing the cost for queries.
In this post, we cover the following topics related to Amazon S3 data partitioning:
- Understanding table metadata in the AWS Glue Data Catalog and S3 partitions for better performance
- How to create a table and load partitions in the Data Catalog using Athena
- How partitions are stored in the table
- Different ways to add partitions in a table on the Data Catalog
- Partitioning data stored in Amazon S3 while ingestion and catalog
Understanding table metadata in the Data Catalog and S3 partitions for better performance
A table in the AWS Glue Data Catalog is the metadata definition that organizes the data location, data type, and column schema, which represents the data in a data store. Partitions are data organized hierarchically, defining the location where the data for a particular partition resides. Partitioning your data allows you to limit the amount of data scanned by S3 SELECT, thereby improving performance and reducing cost.
There are a few factors to consider when deciding the columns on which to partition. For example, if you’re using columns as filters, don’t use a column that is partitioning too finely, or don’t choose a column where your data is heavily skewed to one partition value. You can partition your data by any column. Partition columns are usually designed by a common query pattern in your use case. For example, a common practice is to partition the data based on year/month/day because many queries tend to run time series analyses in typical use cases. This often leads to a multi-level partitioning scheme. Data is organized in a hierarchical directory structure based on the distinct values of one or more columns.
Let’s look at an example of how partitioning works.
Files corresponding to a single day’s worth of data are placed under a prefix such as s3://my_bucket/logs/year=2023/month=06/day=01/.
If your data is partitioned per day, every day you have a single file, such as the following:
s3://my_bucket/logs/year=2023/month=06/day=01/file1_example.jsons3://my_bucket/logs/year=2023/month=06/day=02/file2_example.jsons3://my_bucket/logs/year=2023/month=06/day=03/file3_example.json
We can use a WHERE clause to query the data as follows:
The preceding query reads only the data inside the partition folder year=2023/month=06/day=01 instead of scanning through the files under all partitions. Therefore, it only scans the file file1_example.json.
Systems such as Athena, Amazon Redshift Spectrum, and now AWS Glue can use these partitions to filter data by value, eliminating unnecessary (partition) requests to Amazon S3. This capability can improve the performance of applications that specifically need to read a limited number of partitions. For more information about partitioning with Athena and Redshift Spectrum, refer to Partitioning data in Athena and Creating external tables for Redshift Spectrum, respectively.
How to create a table and load partitions in the Data Catalog using Athena
Let’s begin by understanding how to create a table and load partitions using DDL (Data Definition Language) queries in Athena. Note that to demonstrate the various methods of loading partitions into the table, we need to delete and recreate the table multiple times throughout the following steps.
First, we create a database for this demo.
- On the Athena console, choose Query editor.
If this is your first time using the Athena query editor, you need to configure and specify an S3 bucket to store the query results.
- Create a database with the following command:

- In the Data pane, for Database, choose the database
partitions_blog.

- Create the table
impressionsfollowing the example in Hive JSON SerDe. Replace<myregion>ins3://<myregion>.elasticmapreduce/samples/hive-ads/tables/impressionswith the Region identifier where you run Athena (for example,s3://us-east-1.elasticmapreduce/samples/hive-ads/tables/impressions). - Run the following query to create the table:

The following screenshot shows the query in the query editor.

- Run the following query to review the data:
You can’t see any results because the partitions aren’t loaded yet.

If the partition isn’t loaded into a partitioned table, when the application downloads the partition metadata, the application will not be aware of the S3 path that needs to be queried. For more information, refer to Why do I get zero records when I query my Amazon Athena table.
- Load the partitions using the command
MSCK REPAIR TABLE.

The MSCK REPAIR TABLE command was designed to manually add partitions that are added to or removed from the file system, such as HDFS or Amazon S3, but are not present in the metastore.
- Query the table again to see the results.
After the MSCK REPAIR TABLE command scans Amazon S3 and adds partitions to AWS Glue for Hive-compatible partitions, the records under the registered partitions are now returned.

How partitions are stored in the table metadata
We can list the table partitions in Athena by running the SHOW PARTITIONS command, as shown in the following screenshot.

We also can see the partition metadata on the AWS Glue console. Complete the following steps:
- On the AWS Glue console, choose Tables in the navigation pane under Data Catalog.
- Choose the
impressionstable in thepartitions_blogdatabase.

- On the Partitions tab, choose View Properties next to a partition to view its details.


The following screenshot shows an example of the partition properties.

We can also get the partitions using the AWS Command Line Interface (AWS CLI) command get-partitions, as shown in the following screenshot.

From the get-partitions, the element “Values” defines the partition value and “Location” defines the S3 path to be queried by the application:
When querying the data from the partition dt="2009-04-12-19-05", the application lists and reads only the files in the S3 path s3://us-east-1.elasticmapreduce/samples/hive-ads/tables/impressions/dt="2009-04-12-19-05".
Different ways to add partitions in a table on the Data Catalog
There are multiple ways to load partitions into the table. You can create tables and partitions directly using the AWS Glue API, SDKs, AWS CLI, DDL queries on Athena, using AWS Glue crawlers, or using AWS Glue ETL jobs.
For the next examples, we need to drop and recreate the table. Run the following command in the Athena query editor:

After that, recreate the table:

Creating partitions individually
If the data arrives in an S3 bucket at a scheduled time, for example every hour or once a day, you can individually add partitions. One way of doing so is by running an ALTER TABLE ADD PARTITION DDL query on Athena.
We use Athena for this query as an example. You can do the same from Hive on Amazon EMR, Spark on Amazon EMR, AWS Glue for Apache Spark jobs, and more.
To load partitions using Athena, we need to use the ALTER TABLE ADD PARTITION command, which can create one or more partitions in the table. ALTER TABLE ADD PARTITION supports partitions created on Amazon S3 with camel case (s3://bucket/table/dayOfTheYear=20), Hive format (s3://bucket/table/dayoftheyear=20), and non-Hive style partitioning schemes used by AWS CloudTrail logs, which use separate path components for date parts, such as s3://bucket/data/2021/01/26/us/6fc7845e.json.
To load partitions into a table, you can run the following query in the Athena query editor:

Refer to ALTER TABLE ADD PARTITION for more information.
Another option is using AWS Glue APIs. AWS Glue provides two APIs to load partitions into table create_partition() and batch_create_partition(). For the API parameters, refer to CreatePartition.
The following example uses the AWS CLI:
Both commands (ALTER TABLE in Athena and the AWS Glue API create-partition) will create partition enhancing from the table definition.
Load multiple partitions using MSCK REPAIR TABLE
You can load multiple partitions in Athena. MSCK REPAIR TABLE is a DDL statement that scans the entire S3 path defined in the table’s Location property. Athena lists the S3 path searching for Hive-compatible partitions, then loads the existing partitions into the AWS Glue table’s metadata. A table needs to be created in the Data Catalog, and the data source must be from Amazon S3 before it can run. You can create a table with AWS Glue APIs or by running a CREATE TABLE statement in Athena. After the table creation, run MSCK REPAIR TABLE to load the partitions.

The parameter DDL query timeout in the service quotas defines how long a DDL statement can run. The runtime increases accordingly to the number of folders or partitions in the S3 path.
The MSCK REPAIR TABLE command is best used when creating a table for the first time or when there is uncertainty about parity between data and partition metadata. It supports folders created in lowercase and using Hive-style partitions format (for example, year=2023/month=6/day=01). Because MSCK REPAIR TABLE scans both the folder and its subfolders to find a matching partition scheme, you should keep data for separate tables in separate folder hierarchies.
Every MSCK REPAIR TABLE command lists the entire folder specified in the table location. If you add new partitions frequently (for example, every 5 minutes or every hour), consider scheduling an ALTER TABLE ADD PARTITION statement to load only the partitions defined in the statement instead of scanning the entire S3 path.
The partitions created in the Data Catalog by MSCK REPAIR TABLE enhance the schema from the table definition. Note that Athena doesn’t charge for DDL statements, making MSCK REPAIR TABLE a more straightforward and affordable way to load partitions.
Add multiple partitions using an AWS Glue crawler
An AWS Glue crawler offers more features when loading partitions into the table. A crawler automatically identifies partitions in Amazon S3, extracts metadata, and creates table definitions in the Data Catalog. Crawlers can crawl the following file-based and table-based data stores.
Crawlers can help automate table creation and loading partitions into tables. They are charged per hour, and bill per second. You can optimize the crawler’s performance by altering parameters like the sample size or by specifying it to crawl new folders only.
If the schema of the data changes, the crawler will update the table and partition schemas accordingly. The crawler configuration options have parameters such as update the table definition in the Data Catalog, add new columns only, and ignore the change and don’t update the table in the Data Catalog, which tell the crawler how to update the table when needed and evolve the table schema.
Crawlers can create and update multiple tables from the same data source. When an AWS Glue crawler scans Amazon S3 and detects multiple directories, it uses a heuristic to determine where the root for a table is in the directory structure and which directories are partitions for the table.
To create an AWS Glue crawler, complete the following steps:
- On the AWS Glue console, choose Crawlers in the navigation pane under Data Catalog.
- Choose Create crawler.

- Provide a name and optional description, then choose Next.

- Under Data source configuration, select Not yet and choose Add a data source.

- For Data source, choose S3.
- For S3 path, enter the path of the impression data (
s3://us-east-1.elasticmapreduce/samples/hive-ads/tables/impressions). - Select a preference for subsequent crawler runs.
- Choose Add an S3 data source.

- Select your data source and choose Next.

- Under IAM role, either choose an existing AWS Identity and Access Management (IAM) role or choose Create new IAM role.
- Choose Next.

- For Target database, choose
partitions_blog. - For Table name prefix, enter
crawler_.


We use the table prefix to add a custom prefix in front of the table name. For example, if you leave the prefix field empty and start the crawler on s3://my-bucket/some-table-backup, it creates a table with the name some-table-backup. If you add crawler_ as a prefix, it a creates table called crawler_some-table-backup.
- Choose your crawler schedule, then choose Next.

- Review your settings and create the crawler.
- Select your crawler and choose Run.


Wait for the crawler to finish running.

You can go to Athena and check the table was created:

Partitioning data stored in Amazon S3 while ingestion and cataloging
The previous examples work with data that already exists in Amazon S3. If you’re using AWS Glue jobs to write data on Amazon S3, you have the option to create partitions with DynamicFrames by enabling the “enableUpdateCatalog=True” parameter. Refer to Creating tables, updating the schema, and adding new partitions in the Data Catalog from AWS Glue ETL jobs for more information.
DynamicFrame supports native partitioning using a sequence of keys, using the partitionKeys option when you create a sink. For example, the following Python code writes out a dataset to Amazon S3 in Parquet format into directories partitioned by the ‘year’ field. After ingesting the data and registering partitions from the AWS Glue job, you can utilize these partitions from queries running on other analytics engines such as Athena.
Conclusion
This post showed multiple methods for partitioning your Amazon S3 data, which helps reduce costs by avoiding unnecessary data scanning and also improves the overall performance of your processes. We further described how AWS Glue makes effective metadata management for partitions possible, allowing you to optimize your storage and query operations in AWS Glue and Athena. These partitioning methods can help optimize scanning high volumes of data or long-running queries, as well as reduce the cost of scanning.
We hope you try out these options!
About the authors
 Anderson Santos is a Senior Solutions Architect at Amazon Web Services. He works with AWS Enterprise customers to provide guidance and technical assistance, helping them improve the value of their solutions when using AWS.
 Arun Pradeep Selvaraj is a Senior Solutions Architect and is part of Analytics TFC at AWS. Arun is passionate about working with his customers and stakeholders on digital transformations and innovation in the cloud while continuing to learn, build and reinvent. He is creative, fast-paced, deeply customer-obsessed and leverages the working backwards process to build modern architectures to help customers solve their unique challenges.
 Patrick Muller is a Senior Solutions Architect and a valued member of the Datalab. With over 20 years of expertise in analytics, data warehousing, and distributed systems, he brings extensive knowledge to the table. Patrick’s passion lies in evaluating new technologies and assisting customers with innovative solutions. During his free time, he enjoys watching soccer.







 Chaitanya Shah is a Sr. Technical Account Manager(TAM) with AWS, based out of New York. He has over 22 years of experience working with enterprise customers. He loves to code and actively contributes to the AWS solutions labs to help customers solve complex problems. He provides guidance to AWS customers on best practices for their AWS Cloud migrations. He is also specialized in AWS data transfer and the data and analytics domain.




 Jimish Shah is a Senior Product Manager at AWS with 15+ years of experience bringing products to market in log analytics, cybersecurity, and IP video streaming. He’s passionate about launching products that offer delightful customer experiences, and solve complex customer problems. In his free time, he enjoys exploring cafes, hiking, and taking long walks
 Ross Warren is a Senior Product SA at AWS for Amazon Security Lake based in Northern Virginia. Prior to his work at AWS, Ross’ areas of focus included cyber threat hunting and security operations. When he is not talking about AWS he likes to spend time with his family, bake bread, make sawdust and enjoy time outside.







 Anwar Ali is a Specialist Solutions Architect for Amazon QuickSight. Anwar has over 18 years of experience implementing enterprise business intelligence (BI), data analytics and database solutions . He specializes in integration of BI solutions with business applications, helping customers in BI architecture design patterns and best practices.
 Salim Khan is a Specialist Solutions Architect for Amazon QuickSight. Salim has over 16 years of experience implementing enterprise business intelligence (BI) solutions. Prior to AWS, Salim worked as a BI consultant catering to industry verticals like Automotive, Healthcare, Entertainment, Consumer, Publishing and Financial Services. He has delivered business intelligence, data warehousing, data integration and master data management solutions across enterprises.
 Gil Raviv is a Principal Product Manager for Amazon QuickSight, AWS’ cloud-native, fully managed SaaS BI service. As a thought-leader in BI, Gil accelerated the growth of global BI practices at AWS and Avanade, and has guided Fortune 1000 enterprises in their Data & AI journey. As a passionate evangelist, author and blogger of low-code/no-code data prep and analytic tools, Gil was awarded 5 times as a Microsoft MVP (Most Valuable Professional).


 Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She enjoys building data mesh solutions and sharing them with the community.
 Sandeep Adwankar is a Senior Technical Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.




 Venkata Kampana is a Senior Solutions Architect in the AWS Health and Human Services team and is based in Sacramento, CA. In that role, he helps public sector customers achieve their mission objectives with well-architected solutions on AWS.
 Dr. Dawn Heisey-Grove is the public health analytics leader for Amazon Web Services’ state and local government team. In this role, she’s responsible for helping state and local public health agencies think creatively about how to achieve their analytics challenges and long-term goals. She’s spent her career finding new ways to use existing or new data to support public health surveillance and research.
 Jim Daniel is the Public Health lead at Amazon Web Services. Previously, he held positions with the United States Department of Health and Human Services for nearly a decade, including Director of Public Health Innovation and Public Health Coordinator. Before his government service, Jim served as the Chief Information Officer for the Massachusetts Department of Public Health.

 Ketan Verma is a Senior SDE working on Amazon OpenSearch Service. He is passionate about building large-scale distributed systems, improving performance, and simplifying complex ideas with simple abstractions. Outside work, he likes to read and improve his home barista skills.
 Suresh N S is a Senior SDE working on Amazon OpenSearch Service. He is passionate towards solving problems in large scale distributed systems.
 Pritkumar Ladani is an SDE-2 working on Amazon OpenSearch Service. He likes to contribute to open source software development, and is passionate about distributed systems. He is an amateur badminton player and enjoys trekking.
 Bukhtawar Khan is a Principal Engineer working on Amazon OpenSearch Service. He is interested in building distributed and autonomous systems. He is a maintainer and an active contributor to OpenSearch.

 Ameya Agavekar is a results-driven, highly skilled data strategist. Ameya leads the data engineering and data science function for AWS Professional Services World-Wide Business Insights & Analytics team. Outside of work, Ameya is a professional pilot. He enjoys serving community by applying his unique flying skills with the US Airforce auxiliary Civil Air Patrol.
 Tucker Shouse leads the AWS Professional Services World-Wide Business Insights & Analytics team. Prior to AWS, Tucker worked with financial services, retail, healthcare, and non-profit clients to develop digital and data products and strategies as a Manager at Alvarez & Marsal Corporate Performance Improvement. Outside of work, Tucker enjoys spending time with his wife and daughter enjoying the outdoors and music.


 Nagarjuna Koduru is a Principal Engineer in AWS, currently working for AWS Managed Streaming For Kafka (MSK). He led the teams that built MSK Serverless and MSK Tiered storage products. He previously led the team in Amazon JustWalkOut (JWO) that is responsible for realtime tracking of shopper locations in the store. He played pivotal role in scaling the stateful stream processing infrastructure to support larger store formats and reducing the overall cost of the system. He has keen interest in stream processing, messaging and distributed storage infrastructure.
 Masudur Rahaman Sayem is a Streaming Data Architect at AWS. He works with AWS customers globally to design and build data streaming architectures to solve real-world business problems. He specializes in optimizing solutions that use streaming data services and NoSQL. Sayem is very passionate about distributed computing.
 Nir Tsruya is a Lead Engineer in Klarna. He leads 2 engineering teams focusing mainly on real time data processing and analytics at large scale.
 Ankit Gupta is a Senior Solutions Architect at Amazon Web Serves based in Stockholm, Sweden, where we helps customers across the Nordics succeed in Cloud. He’s particularly passionate about building strong Networking foundation in Cloud.
 Daniel Arenhage is a Solutions Architect at Amazon Web Services based in Gothenburg, Sweden.


 Bhupinder Chadha is a senior product manager for Amazon QuickSight focused on visualization and front end experiences. He is passionate about BI, data visualization and low-code/no-code experiences. Prior to QuickSight he was the lead product manager for Inforiver, responsible for building a enterprise BI product from ground up. Bhupinder started his career in presales, followed by a small gig in consulting and then PM for xViz, an add on visualization product.
 Raji Sivasubramaniam is a Sr. Solutions Architect at AWS, focusing on Analytics. Raji is specialized in architecting end-to-end Enterprise Data Management, Business Intelligence and Analytics solutions for Fortune 500 and Fortune 100 companies across the globe. She has in-depth experience in integrated healthcare data and analytics with wide variety of healthcare datasets including managed market, physician targeting and patient analytics.
 Srikanth Baheti is a Specialized World Wide Principal Solution Architect for Amazon QuickSight. He started his career as a consultant and worked for multiple private and government organizations. Later he worked for PerkinElmer Health and Sciences & eResearch Technology Inc, where he was responsible for designing and developing high traffic web applications, highly scalable and maintainable data pipelines for reporting platforms using AWS services and Serverless computing.

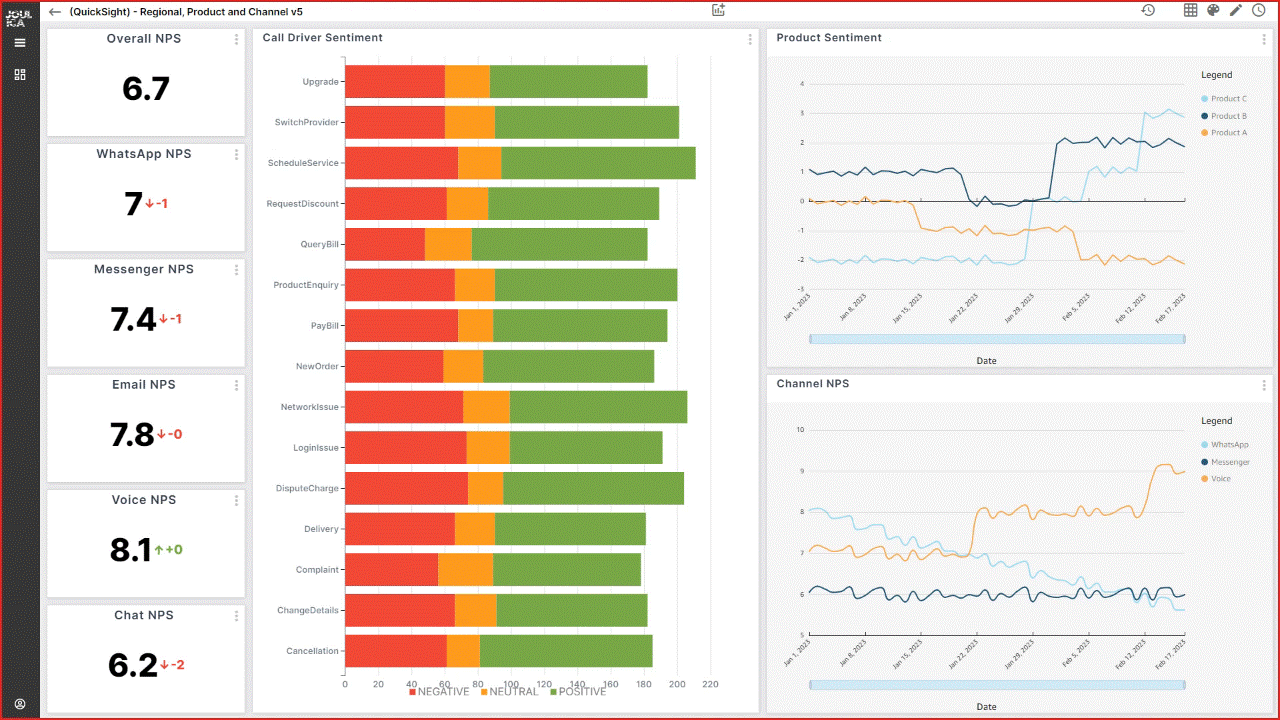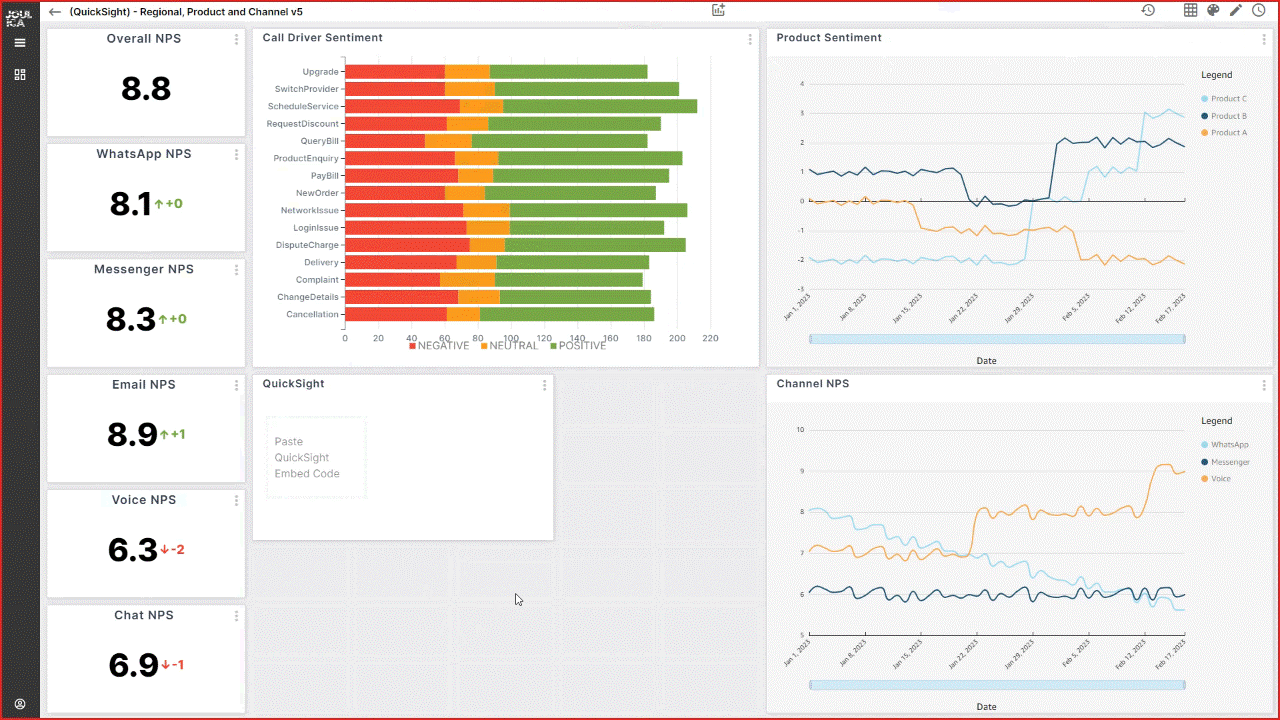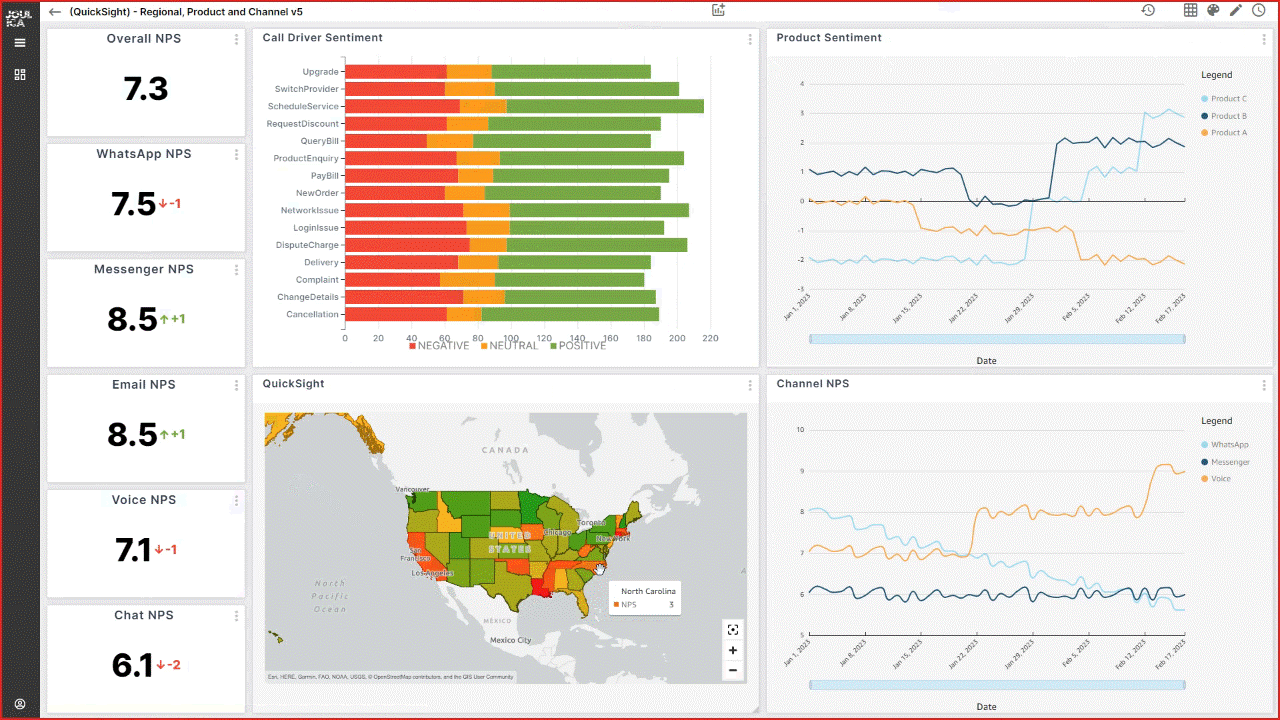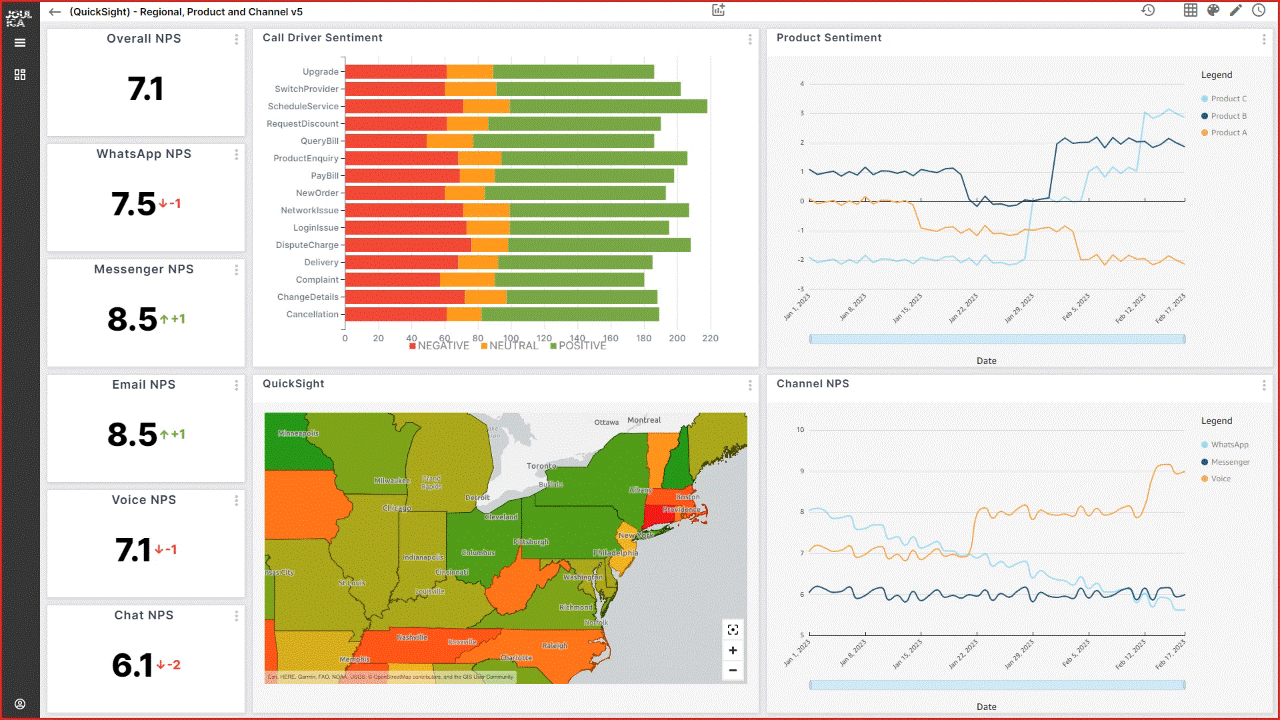
 Tony McCormack is the CEO and Co-founder of Joulica. Based in Galway, Ireland, he is focused on providing enterprise-grade reporting and analytics for Amazon Connect, Salesforce Service Cloud, and other platforms in the customer experience market. He has extensive experience in the contact center domain, with a passion for real-time analytics and their integration into end-user applications.
 Shana Schipers is an Analytics Specialist Solutions Architect at AWS, focusing on big data. She supports customers worldwide in building transactional data lakes using open table formats like Apache Hudi, Apache Iceberg and Delta Lake on AWS.
 Ian Meyers is a Director of Product Management for AWS Analytics Services. He works with many of AWS largest customers on emerging technology needs, and leads several data and analytics initiatives within AWS including support for Data Mesh.




 Vetri Natarajan is a Specialist Solutions Architect for Amazon QuickSight. Vetri has 15 years of experience implementing enterprise business intelligence (BI) solutions and greenfield data products. Vetri specializes in integration of BI solutions with business applications and enable data-driven decisions.
 Zhao Pan is a software development manager for Amazon QuickSight. He is working to provide a delightful developer experience to our customers to automate and streamline their BI operations. He has 20 years of software development experience in various tech stacks. Prior to QuickSight he was a people and technical leader at ADP building a next-gen platform for human capital management. When he is not at his desk, he can usually be found in his garage building one contraption or another.
 Mayank Agarwal is a product manager for Amazon QuickSight, AWS’ cloud-native, fully managed BI service. He focuses on embedded analytics and developer experience. He started his career as an embedded software engineer developing handheld devices. Prior to QuickSight he was leading engineering teams at Credence ID, developing custom mobile embedded device and web solutions using AWS services that make biometric enrollment and identification fast, intuitive, and cost-effective for Government sector, healthcare and transaction security applications.

 Lotfi Mouhib is a Senior Solutions Architect working for the Public Sector team with Amazon Web Services. He helps public sector customers across EMEA realize their ideas, build new services, and innovate for citizens. In his spare time, Lotfi enjoys cycling and running.
 Vara Bonthu is a dedicated technology professional and Worldwide Tech Leader for Data on EKS, specializing in assisting AWS customers ranging from strategic accounts to diverse organizations. He is passionate about open-source technologies, data analytics, AI/ML, and Kubernetes, and boasts an extensive background in development, DevOps, and architecture. Vara’s primary focus is on building highly scalable data and AI/ML solutions on Kubernetes platforms, helping customers harness the full potential of cutting-edge technology for their data-driven pursuits.