Tag Archives: open source

New – Amazon Genomics CLI Is Now Open Source and Generally Available

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-amazon-genomics-cli-is-now-open-source-and-generally-available/

Less than 70 years separate us from one of the greatest discoveries of all time: the double helix structure of DNA. We now know that DNA is a sort of a twisted ladder composed of four types of compounds, called bases. These four bases are usually identified by an uppercase letter: adenine (A), guanine (G), cytosine (C), and thymine (T). One of the reasons for the double helix structure is that when these compounds are at the two sides of the ladder, A always bonds with T, and C always bonds with G.

If we unroll the ladder on a table, we’d see two sequences of “letters”, and each of the two sides would carry the same genetic information. For example, here are two series (AGCT and TCGA) bound together:

A – T
G – C
C – G
T – A

These series of letters can be very long. For example, the human genome is composed of over 3 billion letters of code and acts as the biological blueprint of every cell in a person. The information in a person’s genome can be used to create highly personalized treatments to improve the health of individuals and even the entire population. Similarly, genomic data can be use to track infectious diseases, improve diagnosis, and even track epidemics, food pathogens and toxins. This is the emerging field of environmental genomics.

Accessing genomic data requires genome sequencing, which with recent advances in technology, can be done for large groups of individuals, quickly and more cost-effectively than ever before. In the next five years, genomics datasets are estimated to grow and contain more than a billion sequenced genomes.

How Genomics Data Analysis Works
Genomics data analysis uses a variety of tools that need to be orchestrated as a specific sequence of steps, or a workflow. To facilitate developing, sharing, and running workflows, the genomics and bioinformatics communities have developed specialized workflow definition languages like WDL, Nextflow, CWL, and Snakemake.

However, this process generates petabytes of raw genomic data and experts in genomics and life science struggle to scale compute and storage resources to handle data at such massive scale.

To process data and provide answers quickly, cloud resources like compute, storage, and networking need to be configured to work together with analysis tools. As a result, scientists and researchers often have to spend valuable time deploying infrastructure and modifying open-source genomics analysis tools instead of making contributions to genomics innovations.

Introducing Amazon Genomics CLI
A couple of months ago, we shared the preview of Amazon Genomics CLI, a tool that makes it easier to process genomics data at petabyte scale on AWS. I am excited to share that the Amazon Genomics CLI is now an open source project and is generally available today. You can use it with publicly available workflows as a starting point and develop your analysis on top of these.

Amazon Genomics CLI simplifies and automates the deployment of cloud infrastructure, providing you with an easy-to-use command line interface to quickly setup and run genomics workflows on AWS. By removing the heavy lifting from setting up and running genomics workflows in the cloud, software developers and researchers can automatically provision, configure and scale cloud resources to enable faster and more cost-effective population-level genetics studies, drug discovery cycles, and more.

Amazon Genomics CLI lets you run your workflows on an optimized cloud infrastructure. More specifically, the CLI:

  • Includes improvements to genomics workflow engines to make them integrate better with AWS, removing the burden to manually modify open-source tools and tune them to run efficiently at scale. These tools work seamlessly across Amazon Elastic Container Service (Amazon ECS), Amazon DynamoDB, Amazon Elastic File System (Amazon EFS), and Amazon Simple Storage Service (Amazon S3), helping you to scale compute and storage and at the same time optimize your costs using features like EC2 Spot Instances.
  • Eliminates the most time-consuming tasks like provisioning storage and compute capacities, deploying the genomics workflow engines, and tuning the clusters used to execute workflows.
  • Automatically increases or decreases cloud resources based on your workloads, which eliminates the risk of buying too much or too little capacity.
  • Tags resources so that you can use tools like AWS Cost & Usage Report to understand the costs related to your genomics data analysis across multiple AWS services.

The use of Amazon Genomics CLI is based on these three main concepts:

Workflow – These are bioinformatics workflows written in languages like WDL or Nextflow. They can be either single script files or packages of multiple files. These workflow script files are workflow definitions and combined with additional metadata, like the workflow language the definition is written in, form a workflow specification that is used by the CLI to execute workflows on appropriate compute resources.

Context – A context encapsulates and automates time-consuming tasks to configure and deploy workflow engines, create data access policies, and tune compute clusters (managed using AWS Batch) for operation at scale.

Project – A project links together workflows, datasets, and the contexts used to process them. From a user perspective, it handles resources related to the same problem or used by the same team.

Let’s see how this works in practice.

Using Amazon Genomics CLI
I follow the instructions to install Amazon Genomics CLI on my laptop. Now, I can use the agc command to manage genomic workloads. I see the available options with:

$ agc --help

The first time I use it, I activate my AWS account:

$ agc account activate

This creates the core infrastructure that Amazon Genomics CLI needs to operate, which includes an S3 bucket, a virtual private cloud (VPC), and a DynamoDB table. The S3 bucket is used for durable metadata, and the VPC is used to isolate compute resources.

Optionally, I can bring my own VPC. I can also use one of my named profiles for the AWS Command Line Interface (CLI). In this way, I can customize the AWS Region and the AWS account used by the Amazon Genomics CLI.

I configure my email address in the local settings. This wil be used to tag resources created by the CLI:

$ agc configure email [email protected]

There are a few demo projects in the examples folder included by the Amazon Genomics CLI installation. These projects use different engines, such as Cromwell or Nextflow. In the demo-wdl-project folder, the agc-project.yaml file describes the workflows, the data, and the contexts for the Demo project:

---
name: Demo
schemaVersion: 1
workflows:
  hello:
    type:
      language: wdl
      version: 1.0
    sourceURL: workflows/hello
  read:
    type:
      language: wdl
      version: 1.0
    sourceURL: workflows/read
  haplotype:
    type:
      language: wdl
      version: 1.0
    sourceURL: workflows/haplotype
  words-with-vowels:
    type:
      language: wdl
      version: 1.0
    sourceURL: workflows/words
data:
  - location: s3://gatk-test-data
    readOnly: true
  - location: s3://broad-references
    readOnly: true
contexts:
  myContext:
    engines:
      - type: wdl
        engine: cromwell

  spotCtx:
    requestSpotInstances: true
    engines:
      - type: wdl
        engine: cromwell

For this project, there are four workflows (hello, read, words-with-vowels, and haplotype). The project has read-only access to two S3 buckets and can run workflows using two contexts. Both contexts use the Cromwell engine. One context (spotCtx) uses Amazon EC2 Spot Instances to optimize costs.

In the demo-wdl-project folder, I use the Amazon Genomics CLI to deploy the spotCtx context:

$ agc context deploy -c spotCtx

After a few minutes, the context is ready, and I can execute the workflows. Once started, a context incurs about $0.40 per hour of baseline costs. These costs don’t include the resources created to execute workflows. Those resources depend on your specific use case. Contexts have the option to use spot instances by adding the requestSpotInstances flag to their configuration.

I use the CLI to see the status of the contexts of the project:

$ agc context status

INSTANCE spotCtx STARTED true

Now, let’s look at the workflows included in this project:

$ agc workflow list

2021-09-24T11:15:29+01:00 𝒊  Listing workflows.
WORKFLOWNAME haplotype
WORKFLOWNAME hello
WORKFLOWNAME read
WORKFLOWNAME words-with-vowels

The simplest workflow is hello. The content of the hello.wdl file is quite understandable if you know any programming language:

version 1.0
workflow hello_agc {
    call hello {}
}
task hello {
    command { echo "Hello Amazon Genomics CLI!" }
    runtime {
        docker: "ubuntu:latest"
    }
    output { String out = read_string( stdout() ) }
}

The hello workflow defines a single task (hello) that prints the output of a command. The task is executed on a specific container image (ubuntu:latest). The output is taken from standard output (stdout), the default file descriptor where a process can write output.

Running workflows is an asynchronous process. After submitting a workflow from the CLI, it is handled entirely in the cloud. I can run multiple workflows at a time. The underlying compute resources will automatically scale and I will be charged only for what I use.

Using the CLI, I start the hello workflow:

$ agc workflow run hello -c spotCtx

2021-09-24T13:03:47+01:00 𝒊  Running workflow. Workflow name: 'hello', Arguments: '', Context: 'spotCtx'
fcf72b78-f725-493e-b633-7dbe67878e91

The workflow was successfully submitted, and the last line is the workflow execution ID. I can use this ID to reference a specific workflow execution. Now, I check the status of the workflow:

$ agc workflow status

2021-09-24T13:04:21+01:00 𝒊  Showing workflow run(s). Max Runs: 20
WORKFLOWINSTANCE	spotCtx	fcf72b78-f725-493e-b633-7dbe67878e91	true	RUNNING	2021-09-24T12:03:53Z	hello

The hello workflow is still running. After a few minutes, I check again:

$ agc workflow status

2021-09-24T13:12:23+01:00 𝒊  Showing workflow run(s). Max Runs: 20
WORKFLOWINSTANCE	spotCtx	fcf72b78-f725-493e-b633-7dbe67878e91	true	COMPLETE	2021-09-24T12:03:53Z	hello

The workflow has terminated and is now complete. I look at the workflow logs:

$ agc logs workflow hello

2021-09-24T13:13:08+01:00 𝒊  Showing the logs for 'hello'
2021-09-24T13:13:12+01:00 𝒊  Showing logs for the latest run of the workflow. Run id: 'fcf72b78-f725-493e-b633-7dbe67878e91'
Fri, 24 Sep 2021 13:07:22 +0100	download: s3://agc-123412341234-eu-west-1/scripts/1a82f9a96e387d78ae3786c967f97cc0 to tmp/tmp.498XAhEOy/batch-file-temp
Fri, 24 Sep 2021 13:07:22 +0100	*** LOCALIZING INPUTS ***
Fri, 24 Sep 2021 13:07:23 +0100	download: s3://agc-123412341234-eu-west-1/project/Demo/userid/danilop20tbvT/context/spotCtx/cromwell-execution/hello_agc/fcf72b78-f725-493e-b633-7dbe67878e91/call-hello/script to agc-024700040865-eu-west-1/project/Demo/userid/danilop20tbvT/context/spotCtx/cromwell-execution/hello_agc/fcf72b78-f725-493e-b633-7dbe67878e91/call-hello/script
Fri, 24 Sep 2021 13:07:23 +0100	*** COMPLETED LOCALIZATION ***
Fri, 24 Sep 2021 13:07:23 +0100	Hello Amazon Genomics CLI!
Fri, 24 Sep 2021 13:07:23 +0100	*** DELOCALIZING OUTPUTS ***
Fri, 24 Sep 2021 13:07:24 +0100	upload: ./hello-rc.txt to s3://agc-123412341234-eu-west-1/project/Demo/userid/danilop20tbvT/context/spotCtx/cromwell-execution/hello_agc/fcf72b78-f725-493e-b633-7dbe67878e91/call-hello/hello-rc.txt
Fri, 24 Sep 2021 13:07:25 +0100	upload: ./hello-stderr.log to s3://agc-123412341234-eu-west-1/project/Demo/userid/danilop20tbvT/context/spotCtx/cromwell-execution/hello_agc/fcf72b78-f725-493e-b633-7dbe67878e91/call-hello/hello-stderr.log
Fri, 24 Sep 2021 13:07:25 +0100	upload: ./hello-stdout.log to s3://agc-123412341234-eu-west-1/project/Demo/userid/danilop20tbvT/context/spotCtx/cromwell-execution/hello_agc/fcf72b78-f725-493e-b633-7dbe67878e91/call-hello/hello-stdout.log
Fri, 24 Sep 2021 13:07:25 +0100	*** COMPLETED DELOCALIZATION ***
Fri, 24 Sep 2021 13:07:25 +0100	*** EXITING WITH RETURN CODE ***
Fri, 24 Sep 2021 13:07:25 +0100	0

In the logs, I find as expected the Hello Amazon Genomics CLI! message printed by workflow.

I can also look at the content of hello-stdout.log on S3 using the information in the log above:

aws s3 cp s3://agc-123412341234-eu-west-1/project/Demo/userid/danilop20tbvT/context/spotCtx/cromwell-execution/hello_agc/fcf72b78-f725-493e-b633-7dbe67878e91/call-hello/hello-stdout.log -

Hello Amazon Genomics CLI!

It worked! Now, let’s look for at more complex workflows. Before I change project, I destroy the context for the Demo project:

$ agc context destroy -c spotCtx

In the gatk-best-practices-project folder, I list the available workflows for the project:

$ agc workflow list

2021-09-24T11:41:14+01:00 𝒊  Listing workflows.
WORKFLOWNAME	bam-to-unmapped-bams
WORKFLOWNAME	cram-to-bam
WORKFLOWNAME	gatk4-basic-joint-genotyping
WORKFLOWNAME	gatk4-data-processing
WORKFLOWNAME	gatk4-germline-snps-indels
WORKFLOWNAME	gatk4-rnaseq-germline-snps-indels
WORKFLOWNAME	interleaved-fastq-to-paired-fastq
WORKFLOWNAME	paired-fastq-to-unmapped-bam
WORKFLOWNAME	seq-format-validation

In the agc-project.yaml file, the gatk4-data-processing workflow points to a local directory with the same name. This is the content of that directory:

$ ls gatk4-data-processing

MANIFEST.json
processing-for-variant-discovery-gatk4.hg38.wgs.inputs.json
processing-for-variant-discovery-gatk4.wdl

This workflow processes high-throughput sequencing data with GATK4, a genomic analysis toolkit focused on variant discovery.

The directory contains a MANIFEST.json file. The manifest file describes which file contains the main workflow to execute (there can be more than one WDL file in the directory) and where to find input parameters and options. Here’s the content of the manifest file:

{
  "mainWorkflowURL": "processing-for-variant-discovery-gatk4.wdl",
  "inputFileURLs": [
    "processing-for-variant-discovery-gatk4.hg38.wgs.inputs.json"
  ],
  "optionFileURL": "options.json"
}

In the gatk-best-practices-project folder, I create a context to run the workflows:

$ agc context deploy -c spotCtx

Then, I start the gatk4-data-processing workflow:

$ agc workflow run gatk4-data-processing -c spotCtx

2021-09-24T12:08:22+01:00 𝒊  Running workflow. Workflow name: 'gatk4-data-processing', Arguments: '', Context: 'spotCtx'
630e2d53-0c28-4f35-873e-65363529c3de

After a couple of hours, the workflow has terminated:

$ agc workflow status

2021-09-24T14:06:40+01:00 𝒊  Showing workflow run(s). Max Runs: 20
WORKFLOWINSTANCE	spotCtx	630e2d53-0c28-4f35-873e-65363529c3de	true	COMPLETE	2021-09-24T11:08:28Z	gatk4-data-processing

I look at the logs:

$ agc logs workflow gatk4-data-processing

...
Fri, 24 Sep 2021 14:02:32 +0100	*** DELOCALIZING OUTPUTS ***
Fri, 24 Sep 2021 14:03:45 +0100	upload: ./NA12878.hg38.bam to s3://agc-123412341234-eu-west-1/project/GATK/userid/danilop20tbvT/context/spotCtx/cromwell-execution/PreProcessingForVariantDiscovery_GATK4/630e2d53-0c28-4f35-873e-65363529c3de/call-GatherBamFiles/NA12878.hg38.bam
Fri, 24 Sep 2021 14:03:46 +0100	upload: ./NA12878.hg38.bam.md5 to s3://agc-123412341234-eu-west-1/project/GATK/userid/danilop20tbvT/context/spotCtx/cromwell-execution/PreProcessingForVariantDiscovery_GATK4/630e2d53-0c28-4f35-873e-65363529c3de/call-GatherBamFiles/NA12878.hg38.bam.md5
Fri, 24 Sep 2021 14:03:47 +0100	upload: ./NA12878.hg38.bai to s3://agc-123412341234-eu-west-1/project/GATK/userid/danilop20tbvT/context/spotCtx/cromwell-execution/PreProcessingForVariantDiscovery_GATK4/630e2d53-0c28-4f35-873e-65363529c3de/call-GatherBamFiles/NA12878.hg38.bai
Fri, 24 Sep 2021 14:03:48 +0100	upload: ./GatherBamFiles-rc.txt to s3://agc-123412341234-eu-west-1/project/GATK/userid/danilop20tbvT/context/spotCtx/cromwell-execution/PreProcessingForVariantDiscovery_GATK4/630e2d53-0c28-4f35-873e-65363529c3de/call-GatherBamFiles/GatherBamFiles-rc.txt
Fri, 24 Sep 2021 14:03:49 +0100	upload: ./GatherBamFiles-stderr.log to s3://agc-123412341234-eu-west-1/project/GATK/userid/danilop20tbvT/context/spotCtx/cromwell-execution/PreProcessingForVariantDiscovery_GATK4/630e2d53-0c28-4f35-873e-65363529c3de/call-GatherBamFiles/GatherBamFiles-stderr.log
Fri, 24 Sep 2021 14:03:50 +0100	upload: ./GatherBamFiles-stdout.log to s3://agc-123412341234-eu-west-1/project/GATK/userid/danilop20tbvT/context/spotCtx/cromwell-execution/PreProcessingForVariantDiscovery_GATK4/630e2d53-0c28-4f35-873e-65363529c3de/call-GatherBamFiles/GatherBamFiles-stdout.log
Fri, 24 Sep 2021 14:03:50 +0100	*** COMPLETED DELOCALIZATION ***
Fri, 24 Sep 2021 14:03:50 +0100	*** EXITING WITH RETURN CODE ***
Fri, 24 Sep 2021 14:03:50 +0100	0

Results have been written to the S3 bucket created during the account activation. The name of the bucket is in the logs but I can also find it stored as a parameter by AWS Systems Manager. I can save it in an environment variable with the following command:

$ export AGC_BUCKET=$(aws ssm get-parameter \
  --name /agc/_common/bucket \
  --query 'Parameter.Value' \
  --output text)

Using the AWS Command Line Interface (CLI), I can now explore the results on the S3 bucket and get the outputs of the workflow.

Before looking at the results, I remove the resources that I don’t need by stopping the context. This will destroy all compute resources, but retain data in S3.

$ agc context destroy -c spotCtx

Additional examples on configuring different contexts and running additional workflows are provided in the documentation on GitHub.

Availability and Pricing
Amazon Genomics CLI is an open source tool, and you can use it today in all AWS Regions with the exception of AWS GovCloud (US) and Regions located in China. There is no cost for using the AWS Genomics CLI. You pay for the AWS resources created by the CLI.

With the Amazon Genomics CLI, you can focus on science instead of architecting infrastructure. This gets you up and running faster, enabling research, development, and testing workloads. For production workloads that scale to several thousand parallel workflows, we can provide recommended ways to leverage additional Amazon services, like AWS Step Functions, just reach out to our account teams for more information.

Danilo

New for AWS Distro for OpenTelemetry – Tracing Support is Now Generally Available

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-for-aws-distro-for-opentelemetry-tracing-support-is-now-generally-available/

Last year before re:Invent, we introduced the public preview of AWS Distro for OpenTelemetry, a secure distribution of the OpenTelemetry project supported by AWS. OpenTelemetry provides tools, APIs, and SDKs to instrument, generate, collect, and export telemetry data to better understand the behavior and the performance of your applications. Yesterday, upstream OpenTelemetry announced tracing stability milestone for its components. Today, I am happy to share that support for traces is now generally available in AWS Distro for OpenTelemetry.

Using OpenTelemetry, you can instrument your applications just once and then send traces to multiple monitoring solutions.

You can use AWS Distro for OpenTelemetry to instrument your applications running on Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (EKS), and AWS Lambda, as well as on premises. Containers running on AWS Fargate and orchestrated via either ECS or EKS are also supported.

You can send tracing data collected by AWS Distro for OpenTelemetry to AWS X-Ray, as well as partner destinations such as:

You can use auto-instrumentation agents to collect traces without changing your code. Auto-instrumentation is available today for Java and Python applications. Auto-instrumentation support for Python currently only covers the AWS SDK. You can instrument your applications using other programming languages (such as Go, Node.js, and .NET) with the OpenTelemetry SDKs.

Let’s see how this works in practice for a Java application.

Visualizing Traces for a Java Application Using Auto-Instrumentation
I create a simple Java application that shows the list of my Amazon Simple Storage Service (Amazon S3) buckets and my Amazon DynamoDB tables:

package com.example.myapp;

import software.amazon.awssdk.regions.Region;
import software.amazon.awssdk.services.s3.S3Client;
import software.amazon.awssdk.services.s3.model.*;
import software.amazon.awssdk.services.dynamodb.model.DynamoDbException;
import software.amazon.awssdk.services.dynamodb.model.ListTablesResponse;
import software.amazon.awssdk.services.dynamodb.model.ListTablesRequest;
import software.amazon.awssdk.services.dynamodb.DynamoDbClient;

import java.util.List;

/**
 * Hello world!
 *
 */
public class App {

    public static void listAllTables(DynamoDbClient ddb) {

        System.out.println("DynamoDB Tables:");

        boolean moreTables = true;
        String lastName = null;

        while (moreTables) {
            try {
                ListTablesResponse response = null;
                if (lastName == null) {
                    ListTablesRequest request = ListTablesRequest.builder().build();
                    response = ddb.listTables(request);
                } else {
                    ListTablesRequest request = ListTablesRequest.builder().exclusiveStartTableName(lastName).build();
                    response = ddb.listTables(request);
                }

                List<String> tableNames = response.tableNames();

                if (tableNames.size() > 0) {
                    for (String curName : tableNames) {
                        System.out.format("* %s\n", curName);
                    }
                } else {
                    System.out.println("No tables found!");
                    System.exit(0);
                }

                lastName = response.lastEvaluatedTableName();
                if (lastName == null) {
                    moreTables = false;
                }
            } catch (DynamoDbException e) {
                System.err.println(e.getMessage());
                System.exit(1);
            }
        }

        System.out.println("Done!\n");
    }

    public static void listAllBuckets(S3Client s3) {

        System.out.println("S3 Buckets:");

        ListBucketsRequest listBucketsRequest = ListBucketsRequest.builder().build();
        ListBucketsResponse listBucketsResponse = s3.listBuckets(listBucketsRequest);
        listBucketsResponse.buckets().stream().forEach(x -> System.out.format("* %s\n", x.name()));

        System.out.println("Done!\n");
    }

    public static void listAllBucketsAndTables(S3Client s3, DynamoDbClient ddb) {
        listAllBuckets(s3);
        listAllTables(ddb);
    }

    public static void main(String[] args) {

        Region region = Region.EU_WEST_1;

        S3Client s3 = S3Client.builder().region(region).build();
        DynamoDbClient ddb = DynamoDbClient.builder().region(region).build();

        listAllBucketsAndTables(s3, ddb);

        s3.close();
        ddb.close();
    }
}

I package the application using Apache Maven. Here’s the Project Object Model (POM) file managing dependencies such as the AWS SDK for Java 2.x that I use to interact with S3 and DynamoDB:

<project xmlns="http://maven.apache.org/POM/4.0.0" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 http://maven.apache.org/maven-v4_0_0.xsd">
  <modelVersion>4.0.0</modelVersion>
  <properties>
    <project.build.sourceEncoding>UTF-8</project.build.sourceEncoding>
  </properties>
  <groupId>com.example.myapp</groupId>
  <artifactId>myapp</artifactId>
  <packaging>jar</packaging>
  <version>1.0-SNAPSHOT</version>
  <name>myapp</name>
  <dependencyManagement>
    <dependencies>
      <dependency>
        <groupId>software.amazon.awssdk</groupId>
        <artifactId>bom</artifactId>
        <version>2.17.38</version>
        <type>pom</type>
        <scope>import</scope>
      </dependency>
    </dependencies>
  </dependencyManagement>
  <dependencies>
    <dependency>
      <groupId>junit</groupId>
      <artifactId>junit</artifactId>
      <version>3.8.1</version>
      <scope>test</scope>
    </dependency>
    <dependency>
      <groupId>software.amazon.awssdk</groupId>
      <artifactId>s3</artifactId>
    </dependency>
    <dependency>
      <groupId>software.amazon.awssdk</groupId>
      <artifactId>dynamodb</artifactId>
    </dependency>
  </dependencies>
  <build>
    <plugins>
      <plugin>
        <groupId>org.apache.maven.plugins</groupId>
        <artifactId>maven-compiler-plugin</artifactId>
        <version>3.8.1</version>
        <configuration>
          <source>8</source>
          <target>8</target>
        </configuration>
      </plugin>
      <plugin>
        <artifactId>maven-assembly-plugin</artifactId>
        <configuration>
          <archive>
            <manifest>
              <mainClass>com.example.myapp.App</mainClass>
            </manifest>
          </archive>
          <descriptorRefs>
            <descriptorRef>jar-with-dependencies</descriptorRef>
          </descriptorRefs>
        </configuration>
      </plugin>
    </plugins>
  </build>
</project>

I use Maven to create an executable Java Archive (JAR) file that includes all dependencies:

$ mvn clean compile assembly:single

To run the application and get tracing data, I need two components:

In one terminal, I run the AWS Distro for OpenTelemetry Collector using Docker:

$ docker run --rm -p 4317:4317 -p 55680:55680 -p 8889:8888 \
         -e AWS_REGION=eu-west-1 \
         -e AWS_PROFILE=default \
         -v ~/.aws:/root/.aws \
         --name awscollector public.ecr.aws/aws-observability/aws-otel-collector:latest

The collector is now ready to receive traces and forward them to a monitoring platform. By default, the AWS Distro for OpenTelemetry Collector sends traces to AWS X-Ray. I can change the exporter or add more exporters by editing the collector configuration. For example, I can follow the documentation to configure OLTP exporters to send telemetry data using the OLTP protocol. In the documentation, I also find how to configure other partner destinations. [[ It would be great it we had a link for the partner section, I can find only links to a specific partner ]]

I download the latest version of the AWS Distro for OpenTelemetry Auto-Instrumentation Java Agent. Now, I run my application and use the agent to capture telemetry data without having to add any specific instrumentation the code. In the OTEL_RESOURCE_ATTRIBUTES environment variable I set a name and a namespace for the service: [[ Are service.name and service.namespace being used by X-Ray? I couldn’t find them in the service map ]]

$ OTEL_RESOURCE_ATTRIBUTES=service.name=MyApp,service.namespace=MyTeam \
  java -javaagent:otel/aws-opentelemetry-agent.jar \
       -jar myapp/target/myapp-1.0-SNAPSHOT-jar-with-dependencies.jar

As expected, I get the list of my S3 buckets globally and of the DynamoDB tables in the Region.

To generate more tracing data, I run the previous command a few times. Each time I run the application, telemetry data is collected by the agent and sent to the collector. The collector buffers the data and then sends it to the configured exporters. By default, it is sending traces to X-Ray.

Now, I look at the service map in the AWS X-Ray console to see my application’s interactions with other services:

Console screenshot.

And there they are! Without any change in the code, I see my application’s calls to the S3 and DynamoDB APIs. There were no errors, and all the circles are green. Inside the circles, I find the average latency of the invocations and the number of transactions per minute.

Adding Spans to a Java Application
The information automatically collected can be improved by providing more information with the traces. For example, I might have interactions with the same service in different parts of my application, and it would be useful to separate those interactions in the service map. In this way, if there is an error or high latency, I would know which part of my application is affected.

One way to do so is to use spans or segments. A span represents a group of logically related activities. For example, the listAllBucketsAndTables method is performing two operations, one with S3 and one with DynamoDB. I’d like to group them together in a span. The quickest way with OpenTelemetry is to add the @WithSpan annotation to the method. Because the result of a method usually depends on its arguments, I also use the @SpanAttribute annotation to describe which arguments in the method invocation should be automatically added as attributes to the span.

@WithSpan
    public static void listAllBucketsAndTables(@SpanAttribute("title") String title, S3Client s3, DynamoDbClient ddb) {

        System.out.println(title);

        listAllBuckets(s3);
        listAllTables(ddb);
    }

To be able to use the @WithSpan and @SpanAttribute annotations, I need to import them into the code and add the necessary OpenTelemetry dependencies to the POM. All these changes are based on the OpenTelemetry specifications and don’t depend on the actual implementation that I am using, or on the tool that I will use to visualize or analyze the telemetry data. I have only to make these changes once to instrument my application. Isn’t that great?

To better see how spans work, I create another method that is running the same operations in reverse order, first listing the DynamoDB tables, then the S3 buckets:

    @WithSpan
    public static void listTablesFirstAndThenBuckets(@SpanAttribute("title") String title, S3Client s3, DynamoDbClient ddb) {

        System.out.println(title);

        listAllTables(ddb);
        listAllBuckets(s3);
    }

The application is now running the two methods (listAllBucketsAndTables and listTablesFirstAndThenBuckets) one after the other. For simplicity, here’s the full code of the instrumented application:

package com.example.myapp;

import software.amazon.awssdk.regions.Region;
import software.amazon.awssdk.services.s3.S3Client;
import software.amazon.awssdk.services.s3.model.*;
import software.amazon.awssdk.services.dynamodb.model.DynamoDbException;
import software.amazon.awssdk.services.dynamodb.model.ListTablesResponse;
import software.amazon.awssdk.services.dynamodb.model.ListTablesRequest;
import software.amazon.awssdk.services.dynamodb.DynamoDbClient;

import java.util.List;

import io.opentelemetry.extension.annotations.SpanAttribute;
import io.opentelemetry.extension.annotations.WithSpan;

/**
 * Hello world!
 *
 */
public class App {

    public static void listAllTables(DynamoDbClient ddb) {

        System.out.println("DynamoDB Tables:");

        boolean moreTables = true;
        String lastName = null;

        while (moreTables) {
            try {
                ListTablesResponse response = null;
                if (lastName == null) {
                    ListTablesRequest request = ListTablesRequest.builder().build();
                    response = ddb.listTables(request);
                } else {
                    ListTablesRequest request = ListTablesRequest.builder().exclusiveStartTableName(lastName).build();
                    response = ddb.listTables(request);
                }

                List<String> tableNames = response.tableNames();

                if (tableNames.size() > 0) {
                    for (String curName : tableNames) {
                        System.out.format("* %s\n", curName);
                    }
                } else {
                    System.out.println("No tables found!");
                    System.exit(0);
                }

                lastName = response.lastEvaluatedTableName();
                if (lastName == null) {
                    moreTables = false;
                }
            } catch (DynamoDbException e) {
                System.err.println(e.getMessage());
                System.exit(1);
            }
        }

        System.out.println("Done!\n");
    }

    public static void listAllBuckets(S3Client s3) {

        System.out.println("S3 Buckets:");

        ListBucketsRequest listBucketsRequest = ListBucketsRequest.builder().build();
        ListBucketsResponse listBucketsResponse = s3.listBuckets(listBucketsRequest);
        listBucketsResponse.buckets().stream().forEach(x -> System.out.format("* %s\n", x.name()));

        System.out.println("Done!\n");
    }

    @WithSpan
    public static void listAllBucketsAndTables(@SpanAttribute("title") String title, S3Client s3, DynamoDbClient ddb) {

        System.out.println(title);

        listAllBuckets(s3);
        listAllTables(ddb);

    }

    @WithSpan
    public static void listTablesFirstAndThenBuckets(@SpanAttribute("title") String title, S3Client s3, DynamoDbClient ddb) {

        System.out.println(title);

        listAllTables(ddb);
        listAllBuckets(s3);

    }

    public static void main(String[] args) {

        Region region = Region.EU_WEST_1;

        S3Client s3 = S3Client.builder().region(region).build();
        DynamoDbClient ddb = DynamoDbClient.builder().region(region).build();

        listAllBucketsAndTables("My S3 buckets and DynamoDB tables", s3, ddb);
        listTablesFirstAndThenBuckets("My DynamoDB tables first and then S3 bucket", s3, ddb);

        s3.close();
        ddb.close();
    }
}

And here’s the updated POM that includes the additional OpenTelemetry dependencies:

<project xmlns="http://maven.apache.org/POM/4.0.0" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 http://maven.apache.org/maven-v4_0_0.xsd">
  <modelVersion>4.0.0</modelVersion>
  <properties>
    <project.build.sourceEncoding>UTF-8</project.build.sourceEncoding>
  </properties>
  <groupId>com.example.myapp</groupId>
  <artifactId>myapp</artifactId>
  <packaging>jar</packaging>
  <version>1.0-SNAPSHOT</version>
  <name>myapp</name>
  <dependencyManagement>
    <dependencies>
      <dependency>
        <groupId>software.amazon.awssdk</groupId>
        <artifactId>bom</artifactId>
        <version>2.16.60</version>
        <type>pom</type>
        <scope>import</scope>
      </dependency>
    </dependencies>
  </dependencyManagement>
  <dependencies>
    <dependency>
      <groupId>junit</groupId>
      <artifactId>junit</artifactId>
      <version>3.8.1</version>
      <scope>test</scope>
    </dependency>
    <dependency>
      <groupId>software.amazon.awssdk</groupId>
      <artifactId>s3</artifactId>
    </dependency>
    <dependency>
      <groupId>software.amazon.awssdk</groupId>
      <artifactId>dynamodb</artifactId>
    </dependency>
    <dependency>
      <groupId>io.opentelemetry</groupId>
      <artifactId>opentelemetry-extension-annotations</artifactId>
      <version>1.5.0</version>
    </dependency>
    <dependency>
      <groupId>io.opentelemetry</groupId>
      <artifactId>opentelemetry-api</artifactId>
      <version>1.5.0</version>
    </dependency>
  </dependencies>
  <build>
    <plugins>
      <plugin>
        <groupId>org.apache.maven.plugins</groupId>
        <artifactId>maven-compiler-plugin</artifactId>
        <version>3.8.1</version>
        <configuration>
          <source>8</source>
          <target>8</target>
        </configuration>
      </plugin>
      <plugin>
        <artifactId>maven-assembly-plugin</artifactId>
        <configuration>
          <archive>
            <manifest>
              <mainClass>com.example.myapp.App</mainClass>
            </manifest>
          </archive>
          <descriptorRefs>
            <descriptorRef>jar-with-dependencies</descriptorRef>
          </descriptorRefs>
        </configuration>
      </plugin>
    </plugins>
  </build>
</project>

I compile my application with these changes and run it again a few times:

$ mvn clean compile assembly:single

$ OTEL_RESOURCE_ATTRIBUTES=service.name=MyApp,service.namespace=MyTeam \
  java -javaagent:otel/aws-opentelemetry-agent.jar \
       -jar myapp/target/myapp-1.0-SNAPSHOT-jar-with-dependencies.jar

Now, let’s look at the X-Ray service map, computed using the additional information provided by those annotations.

Console screenshot.

Now I see the two methods and the other services they invoke. If there are errors or high latency, I can easily understand how the two methods are affected.

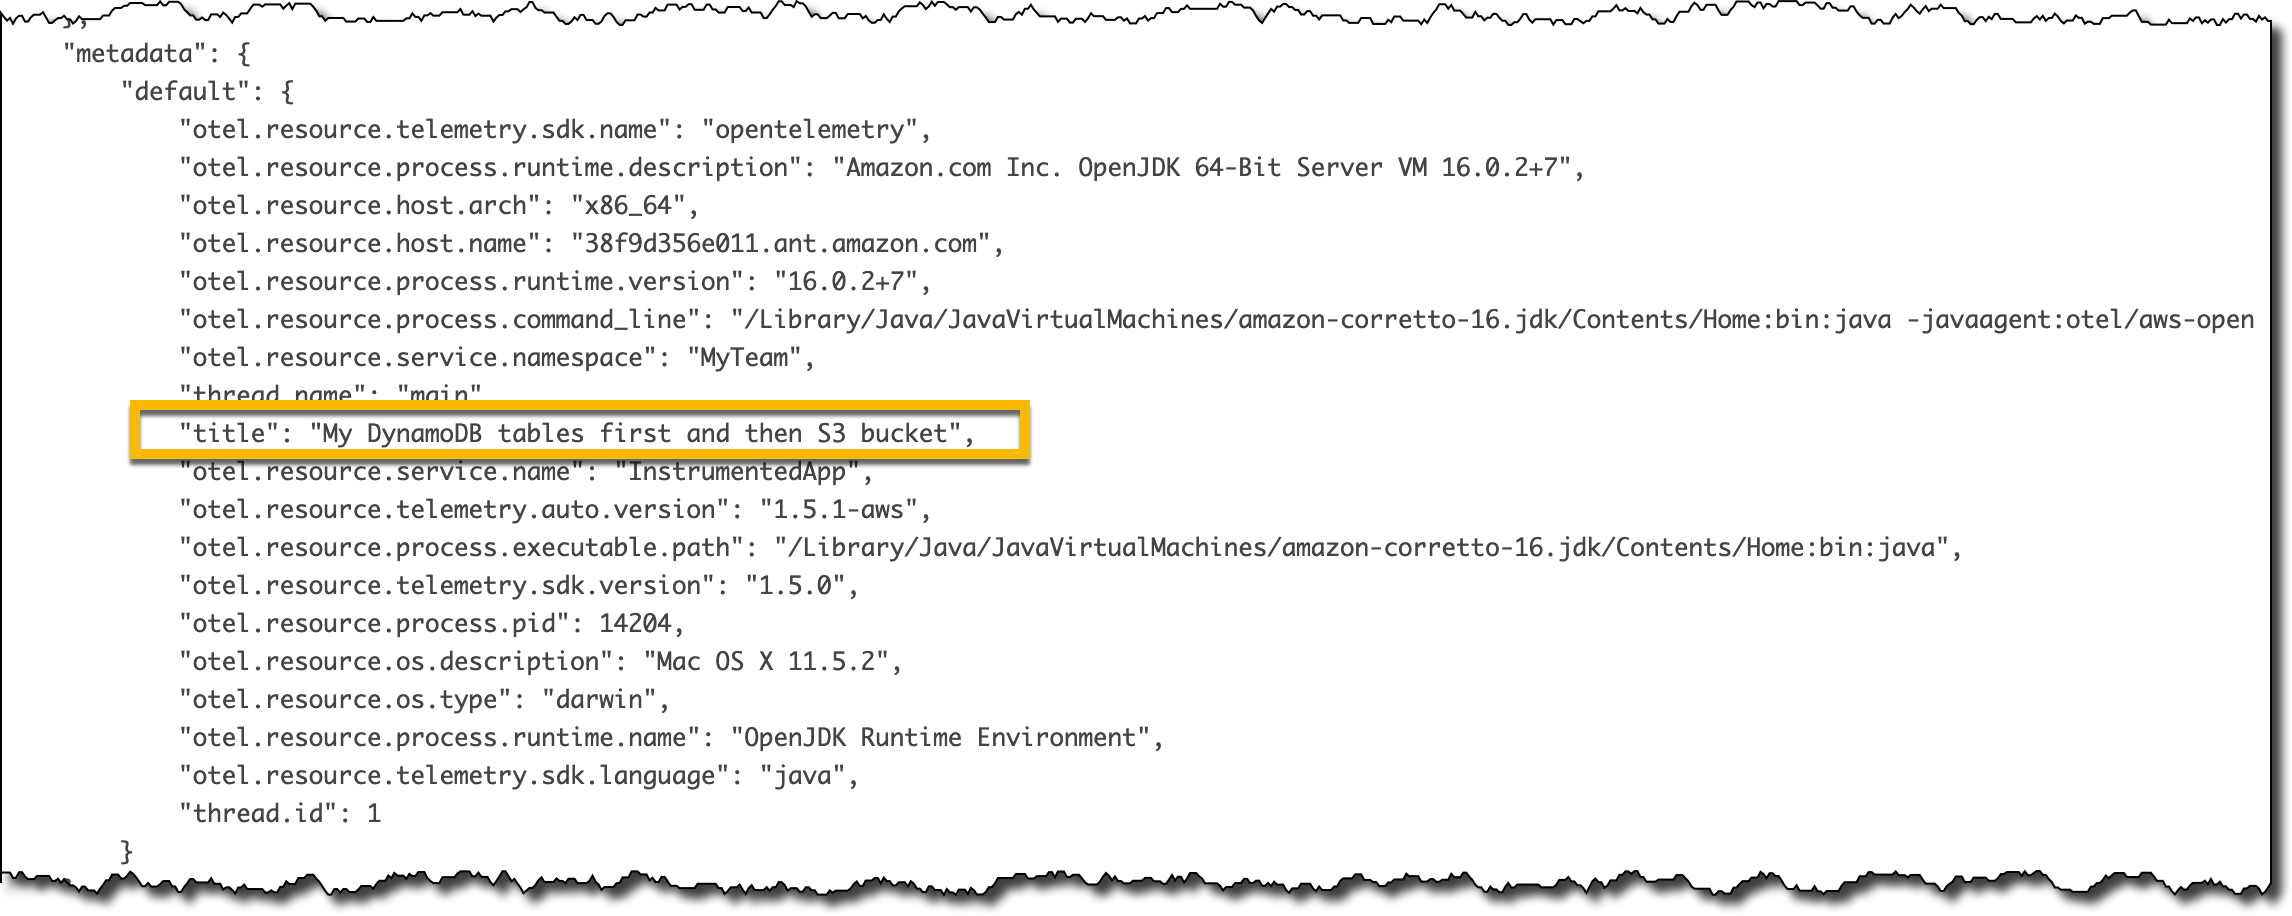
In the Traces section of the X-Ray console, I look at the Raw data for some of the traces. Because the title argument was annotated with @SpanAttribute, each trace has the value of that argument in the metadata section.

Console screenshot.

Collecting Traces from Lambda Functions
The previous steps work on premises, on EC2, and with applications running in containers. To collect traces and use auto-instrumentation with Lambda functions, you can use the AWS managed OpenTelemetry Lambda Layers (a few examples are included in the repository).

After you add the Lambda layer to your function, you can use the environment variable OPENTELEMETRY_COLLECTOR_CONFIG_FILE to pass your own configuration to the collector. More information on using AWS Distro for OpenTelemetry with AWS Lambda is available in the documentation.

Availability and Pricing
You can use AWS Distro for OpenTelemetry to get telemetry data from your application running on premises and on AWS. There are no additional costs for using AWS Distro for OpenTelemetry. Depending on your configuration, you might pay for the AWS services that are destinations for OpenTelemetry data, such as AWS X-Ray, Amazon CloudWatch, and Amazon Managed Service for Prometheus (AMP).

To learn more, you are invited to this webinar on Thursday, October 7 at 10:00 am PT / 1:00 pm EDT / 7:00 pm CEST.

Simplify the instrumentation of your applications and improve their observability using AWS Distro for OpenTelemetry today.

Danilo

Amazon EKS Anywhere – Now Generally Available to Create and Manage Kubernetes Clusters on Premises

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/amazon-eks-anywhere-now-generally-available-to-create-and-manage-kubernetes-clusters-on-premises/

At AWS re:Invent 2020, we preannounced new deployment options of Amazon Elastic Container Service (Amazon ECS) Anywhere and Amazon Elastic Kubernetes Service (Amazon EKS) Anywhere in your own data center.

Today, I am happy to announce the general availability of Amazon EKS Anywhere, a deployment option for Amazon EKS that enables you to easily create and operate Kubernetes clusters on premises using VMware vSphere starting today. EKS Anywhere provides an installable software package for creating and operating Kubernetes clusters on premises and automation tooling for cluster lifecycle support.

EKS Anywhere brings a consistent AWS management experience to your data center, building on the strengths of Amazon EKS Distro, an open-source distribution for Kubernetes used by Amazon EKS.

EKS Anywhere is also Open Source. You can reduce the complexity of buying or building your own management tooling to create EKS Distro clusters, configure the operating environment, and update software. EKS Anywhere enables you to automate cluster management, reduce support costs, and eliminate the redundant effort of using multiple open-source or third-party tools for operating Kubernetes clusters. EKS Anywhere is fully supported by AWS. In addition, you can leverage the EKS console to view all your Kubernetes clusters, running anywhere.

We provide several deployment options for your Kubernetes cluster:

Feature Amazon EKS EKS on Outposts EKS Anywhere EKS Distro
Hardware Managed by AWS Managed by customer
Deployment types Amazon EC2, AWS Fargate (Serverless) EC2 on Outposts Customer Infrastructure
Control plane management Managed by AWS Managed by customer
Control plane location AWS cloud Customer’s on-premises or data center
Cluster updates Managed in-place update process for control plane and data plane CLI (Flux supported rolling update for data plane, manual update for control plane)
Networking and Security Amazon VPC Container Network Interface (CNI), Other compatible 3rd party CNI plugins Cilium CNI 3rd party CNI plugins
Console support Amazon EKS console EKS console using EKS Connector Self-service
Support AWS Support EKS Anywhere support subscription Self-service

EKS Anywhere integrates with a variety of products from our partners to help customers take advantage of EKS Anywhere and provide additional functionality. This includes Flux for cluster updates, Flux Controller for GitOps, eksctl – a simple CLI tool for creating and managing clusters on EKS, and Cilium for networking and security.

We also provide flexibility for you to integrate with your choice of tools in other areas. To add integrations to your EKS Anywhere cluster, see this list of suggested third-party tools for your consideration.

Get Started with Amazon EKS Anywhere
To get started with EKS Anywhere, you can create a bootstrap cluster in your machine for local development and test purposes. Currently, it allows you to create clusters in a VMWare vSphere environment for production workloads.

Let’s create a cluster on your desktop machine using eksctl! You can install eksctl and eksctl-anywhere with homebrew on Mac. Optionally, you can install some additional tools you may want for your EKS Anywhere clusters, such as kubectl. To learn more on Linux, see the installation guide in EKS Anywhere documentation.

$ brew install aws/tap/eks-anywhere
$ eksctl anywhere version
0.63.0

Generate a cluster config and create a cluster.

$ CLUSTER_NAME=dev-cluster
$ eksctl anywhere generate clusterconfig $CLUSTER_NAME \
    --provider docker > $CLUSTER_NAME.yaml
$ eksctl anywhere create cluster -f $CLUSTER_NAME.yaml
[i] Performing setup and validations
[v] validation succeeded {"validation": "docker Provider setup is valid"}
[i] Creating new bootstrap cluster
[i] Installing cluster-api providers on bootstrap cluster
[i] Provider specific setup
[i] Creating new workload cluster
[i] Installing networking on workload cluster
[i] Installing cluster-api providers on workload cluster
[i] Moving cluster management from bootstrap to workload cluster
[i] Installing EKS-A custom components (CRD and controller) on workload cluster
[i] Creating EKS-A CRDs instances on workload cluster
[i] Installing AddonManager and GitOps Toolkit on workload cluster
[i] GitOps field not specified, bootstrap flux skipped
[i] Deleting bootstrap cluster
[v] Cluster created!

Once your workload cluster is created, a KUBECONFIG file is stored on your admin machine with admin permissions for the workload cluster. You’ll be able to use that file with kubectl to set up and deploy workloads.

$ export KUBECONFIG=${PWD}/${CLUSTER_NAME}/${CLUSTER_NAME}-eks-a-cluster.kubeconfig
$ kubectl get ns
NAME                                STATUS   AGE
capd-system                         Active   21m
capi-kubeadm-bootstrap-system       Active   21m
capi-kubeadm-control-plane-system   Active   21m
capi-system                         Active   21m
capi-webhook-system                 Active   21m
cert-manager                        Active   22m
default                             Active   23m
eksa-system                         Active   20m
kube-node-lease                     Active   23m
kube-public                         Active   23m
kube-system                         Active   23m

You can create a simple test application for you to verify your cluster is working properly. Deploy and see a new pod running in your cluster, and forward the deployment port to your local machine with the following commands:

$ kubectl apply -f "https://anywhere.eks.amazonaws.com/manifests/hello-eks-a.yaml"
$ kubectl get pods -l app=hello-eks-a
NAME                                     READY   STATUS    RESTARTS   AGE
hello-eks-a-745bfcd586-6zx6b   1/1     Running   0          22m
$ kubectl port-forward deploy/hello-eks-a 8000:80
$ curl localhost:8000
⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢

Thank you for using

███████╗██╗  ██╗███████╗
██╔════╝██║ ██╔╝██╔════╝
█████╗  █████╔╝ ███████╗
██╔══╝  ██╔═██╗ ╚════██║
███████╗██║  ██╗███████║
╚══════╝╚═╝  ╚═╝╚══════╝

 █████╗ ███╗   ██╗██╗   ██╗██╗    ██╗██╗  ██╗███████╗██████╗ ███████╗
██╔══██╗████╗  ██║╚██╗ ██╔╝██║    ██║██║  ██║██╔════╝██╔══██╗██╔════╝
███████║██╔██╗ ██║ ╚████╔╝ ██║ █╗ ██║███████║█████╗  ██████╔╝█████╗  
██╔══██║██║╚██╗██║  ╚██╔╝  ██║███╗██║██╔══██║██╔══╝  ██╔══██╗██╔══╝  
██║  ██║██║ ╚████║   ██║   ╚███╔███╔╝██║  ██║███████╗██║  ██║███████╗
╚═╝  ╚═╝╚═╝  ╚═══╝   ╚═╝    ╚══╝╚══╝ ╚═╝  ╚═╝╚══════╝╚═╝  ╚═╝╚══════╝

You have successfully deployed the hello-eks-a pod hello-eks-a-c5b9bc9d8-qp6bg

For more information check out
https://anywhere.eks.amazonaws.com

⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢⬡⬢

EKS Anywhere also supports a VMWare vSphere 7.0 version or higher for production clusters. To create a production cluster, see the requirements for VMware vSphere deployment and follow Create production cluster in EKS Anywhere documentation. It’s almost the same process as creating a test cluster on your machine.

A production-grade EKS Anywhere cluster should include at least three control plane nodes and three worker nodes on the vSphere for high availability and rolling upgrades. See the Cluster management in EKS Anywhere documentation for more information on common operational tasks like scaling, updating, and deleting the cluster.

EKS Connector – Public Preview
EKS Connector is a new capability that allows you to connect any Kubernetes clusters to the EKS console. You can connect any Kubernetes cluster, including self-managed clusters on EC2, EKS Anywhere clusters running on premises, and other Kubernetes clusters running outside of AWS to the EKS console. It makes it easy for you to view all connected clusters centrally.

To connect your EKS Anywhere cluster, visit the Clusters section in EKS console and select Register in the Add cluster drop-down menu.

Define a name for your cluster and select the Provider (if you don’t find an appropriate provider, select Other).

After registering the cluster, you will be redirected to the Cluster Overview page. Select  Download YAML file to get the Kubernetes configuration file to deploy all the necessary infrastructure to connect your cluster to EKS.

Apply downloaded eks-connector.yaml and role binding eks-connector-binding.yaml file from the EKS Connector in our documentation. EKS Connector acts as a proxy and forwards the EKS console requests to the Kubernetes API server on your cluster, so you need to associate the connector’s service account with an EKS Connector Role, which gives permission to impersonate AWS IAM entities.

$ kubectl apply -f eks-connector.yaml
$ kubectl apply -f eks-connector-binding.yaml

After completing the registration, the cluster should be in the ACTIVE state.

$ eks describe-cluster --name "my-first-registered-cluster" --region ${AWS_REGION}

Here is the expected output:

{
    "cluster": {
    "name": "my-first-registered-cluster",
    "arn": "arn:aws:eks:{EKS-REGION}:{ACCOUNT-ID}:cluster/my-first-registered-cluster", 
    "createdAt": 1627672425.765,
    "connectorConfig": {
    "activationId": "xxxxxxxxACTIVATION_IDxxxxxxxx", 
    "activationExpiry": 1627676019.0,
    "provider": "OTHER",
     "roleArn": "arn:aws:iam::{ACCOUNT-ID}:role/eks-connector-agent"
    },
  "status": "ACTIVE", "tags": {}
  } 
}

EKS Connector is now in public preview in all AWS Regions where Amazon EKS is available. Please choose a region that’s closest to your cluster location to minimize latency. To learn more, visit EKS Connector in the Amazon EKS User Guide.

Things to Know
Here are a couple of things to keep in mind about EKS Anywhere:

Connectivity: There are three connectivity options: fully connected, partially disconnected, and fully disconnected. For fully connected and partially disconnected connectivity, you can connect your EKS Anywhere clusters to the EKS console via the EKS Connector and see the cluster configuration and workload status. You can leverage AWS services through AWS Controllers for Kubernetes (ACK). You can connect EKS Anywhere infrastructure resources using AWS System Manager Agents and view them using the SSM console.

Security Model: AWS follows the Shared Responsibility Model, where AWS is responsible for the security of the cloud, while the customer is responsible for security in the cloud. However, EKS Anywhere is an open-source tool, and the distribution of responsibility differs from that of a managed cloud service like Amazon EKS. AWS is responsible for building and delivering a secure tool. This tool will provision an initially secure Kubernetes cluster. To learn more, see Security Best Practices in EKS Anywhere documentation.

AWS Support: AWS Enterprise Support is a prerequisite for purchasing an Amazon EKS Anywhere Support subscription. If you would like business support for your EKS Anywhere clusters, please contact your Technical Account Manager (TAM) for details. Also, EKS Anywhere is supported by the open-source community. If you have a problem, open an issue and someone will get back to you as soon as possible.

Available Now
Amazon EKS Anywhere is now available to leverage EKS features with your on-premise infrastructure, accelerate adoption with partner integrations, managed add-ons, and curated open-source tools.

To learn more with a live demo and Q&A, join us for Containers from the Couch on September 13. You can see full demos to create a cluster and show admin workflows for scaling, upgrading the cluster version, and GitOps management.

Please send us feedback either through your usual AWS Support contacts, on the AWS Forum for Amazon EKS or on the container roadmap on Github.

Channy

Security at Scale in the Open-Source Supply Chain

Post Syndicated from Aaron Wells original https://blog.rapid7.com/2021/09/08/security-at-scale-in-the-open-source-supply-chain/

Security at Scale in the Open-Source Supply Chain

“We’ve all heard of paying it forward, but this is ridiculous!” That’s probably what most of us think when one of our partners or vendors inadvertently leaves an open door into our shared supply-chain network; an attacker can enter at any time. Well, we probably think in slightly more expletive-laden terms, but nonetheless, no organization or company wants to be the focal point of blame from a multitude of (formerly) trusting partners or vendors.

Open-source software (OSS) is particularly susceptible to these vulnerabilities. OSS is simultaneously incredible and incredibly vulnerable. In fact, there are so many risks that can result from largely structuring operations on OSS that vendors may not prioritize patching a vulnerability once their security team is alerted. And can we blame them? They want to continue operations and feed the bottom line, not put a pause on operations to forever chase vulnerabilities and patch them one-by-one. But that leaves all of their supply-chain partners open to exploitation. What to do?

The supply-chain scene

Throughout a 12-month timeframe spanning 2019-2020, attacks aimed at OSS increased 430%, according to a study by Sonatype. It’s not quite as simple as “gain access to one, gain access to all,” but if a bad actor is properly motivated, this is exactly what can happen. In terms of motivation, supply-chain attackers can fall into 2 groups:

  • Bandwagoners: Attackers falling into this group will often wait for public disclosure of supply-chain vulnerabilities.
  • Ahead-of-the-curvers: Attackers falling into this group will actively hunt for and exploit vulnerabilities, saddling the unfortunate organization with malware and threatening its entire supply chain.

To add to the favor of attackers, the same Sonatype study also found that a shockingly low percentage of security organizations do not even learn of new open-source vulnerabilities in the short term after they’re disclosed. Sure, everyone’s busy and has their priorities. But that ethos exists while these vulnerabilities are being exploited. Perhaps the project was shipped on time, but malicious code was simultaneously being injected somewhere along the line. Then, instead of continuing with forward progress, remediation becomes the name of the game.  

According to the Sonatype report, there were more than a trillion open-source component and container download requests in 2020 alone. The most important aspects to consider then are the security history of your component(s) and how dependents along your supply chain are using them. Obviously, this can be overwhelming to think about, but with researchers increasingly focused on remediation at scale, the future of supply-chain security is starting to look brighter.

Learn more about open-source security + win some cash!

Submit to the 2021 Velociraptor Contributor Competition

Securing at scale

Instead of the one-by-one approach to patching, security professionals need to start thinking about securing entire classes of vulnerabilities. It’s true that there is no current catch-all mechanism for such efficient action. But researchers can begin to work together to create methodologies that enable security organizations to better prioritize vulnerability risk management (VRM) instead of filing each one away to patch at a later date.

Of course, preventive security measures — inclusive of our shift-left culture — can help to mitigate the need to scale such remediation actions; the fact remains though that bad actors will always find a way. Therefore, until there are effective ways to eliminate large swaths of vulnerabilities at once, there is a growing need for teams to adhere to current best practices and measures like:  

  • Dedicating time and resources to help ensure code is secure all along the chain
  • Thinking holistically about the security of open-source code with regard to the CI/CD lifecycle and the entire stack
  • Being willing to pitch in and develop coordinated, industry-wide efforts to improve the security of OSS at scale
  • Educating outside stakeholders on just how interdependent supply-chain-linked organizations are

As supply-chain attackers refine their methods to target ever-larger companies, the pressure is on developers to refine their understanding of how each and every contributor on a team can expose the organization and its partners along the chain, as The Linux Foundation points out. However, is this too much to put on the shoulders of DevOps? Shifting left to a DevSecOps culture is great and all, but teams are now being asked to think in the context of securing an entire supply chain’s worth of output.

This is why the industry at large must continue the push for research into new ways to eliminate entire classes of vulnerabilities. That’s a seismic shift left that will only help developers — and really, everyone — put more energy into things other than security.

Monitoring mindfully

While a proliferation of OSS components — as advantageous as they are for collaboration at scale — can make a supply chain vulnerable, the power of one open-source community can help monitor another open-source community. Velociraptor by Rapid7 is an open-source digital forensics and incident response (DFIR) platform.

This powerful DFIR tool thrives in loaded conditions. It can quickly scale incident response and monitoring and help security organizations to better prioritize remediation — actions well-suited to address the scale of modern supply-chain attacks. How quickly organizations choose to respond to incidents or vulnerabilities is, of course, up to them.

Supply chain security is ever-evolving

If one link in the chain is attacked via a long-languishing vulnerability whose risk has increasingly become harder to manage, it almost goes without saying that company’s partners or vendors immediately lose confidence in it because the entire chain is now at risk. The public’s confidence likely will follow.

There are any number of preventive measures an interdependent security organization can implement. However, the need for further research into scaling security for whole classes of vulnerabilities comes at a crucial time as global supply-chain attacks more frequently occur in all shapes and sizes.

Want to contribute to a more secure open-source future?

Submit to the 2021 Velociraptor Contributor Competition

Top 5 reasons to choose Zabbix for network monitoring

Post Syndicated from Dmitry Lambert original https://blog.zabbix.com/top-5-reasons-to-choose-zabbix-for-network-monitoring/15247/

There are many monitoring solutions and monitoring tools that you can use for different monitoring tasks. But in this post and video, we will focus only on Zabbix and the top five features making Zabbix the best choice to monitor your home office as well as enterprise instances or projects.

Contents

I. Free and open-source solution (0:44)
II. Wide functionality (1:43)
III. No access to your data (03:53)
IV. Balance of flexibility and simplicity (5:35)
V. Commercial services (7:55)

Free and open-source solution

First, Zabbix is a free and open-source solution covered by General Public License (GPL) v2. This means that the Zabbix source code is readily available and can be redistributed or modified. With this in mind, you can always create your own version of Zabbix, if you’re willing to play around with the source code or have a great idea on how to improve the product.

Zabbix software properties

There are no paid versions of Zabbix, no paid functionality, and no hidden costs. You can monitor any number of devices and define your own data retention policies at no cost at all.

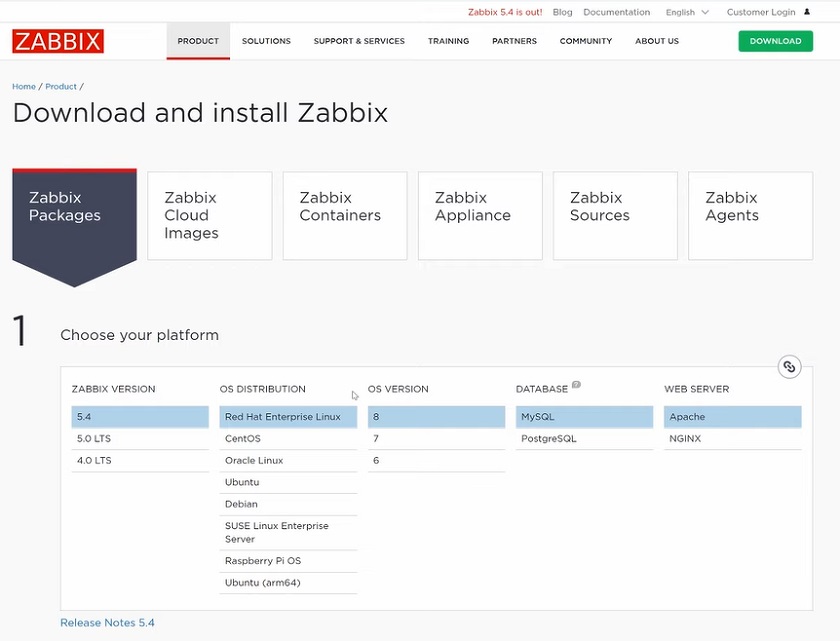
All of the latest features are absolutely free and available in the latest version of Zabbix. You can visit zabbix.com, click the Download button, choose the platform that is best for you and install Zabbix packages on it. Zabbix can be deployed on any kind of environment, be it a virtual machine, physical servers, cloud environments, or even a Docker container. After you have downloaded Zabbix, you are ready to go ahead with the latest Zabbix feature set.

Selecting platform to install Zabbix n Zabbix.com/download

Rich feature set

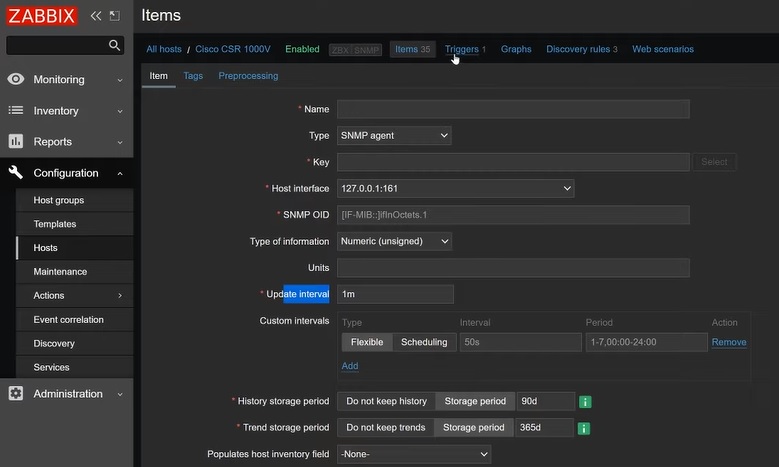
Zabbix is a fully enterprise-ready product with a wide set of features that you can use to achieve any of your monitoring tasks. As a tool, Zabbix is not focused on any single thing, offering users extreme flexibility. For instance, you can monitor Windows or Linux machines agentlessly or opt-in to install a Zabbix agent on them. On the other hand, to monitor network devices, SNMP monitoring might be the easiest approach. All it takes to start monitoring your end-points is creating an item, specifying the metric that you want to monitor together with the data collection interval, and you are good to go.

Configuring SNMP monitoring parameters

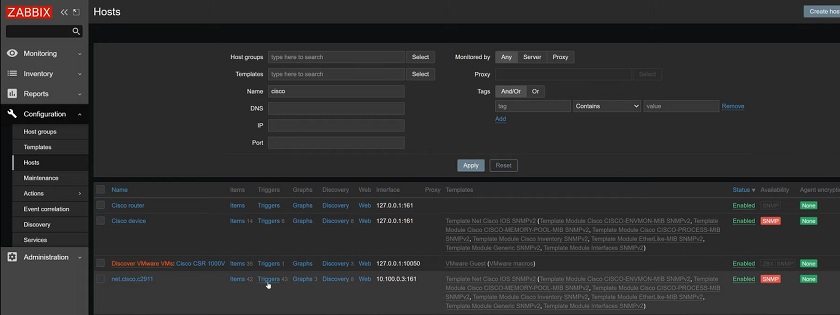
After we have collected the data, we can configure our problem thresholds (also known as triggers in Zabbix) by navigating to Configuration > Hosts > Triggers. Triggers are definitions of our problem thresholds, where you can define a problem threshold, when do you consider your metric to be within that threshold and how do you recover from the problem.

There is a wide array of so called trigger functions – these allow us to define thresholds in different ways. For example, we can analyze the last received value, averages, minimum and maximum values over some time, look for a specific string in a value and much, much more!


We also need to define a way of reacting to a problem – should we receive an e-mail if something goes wrong? Or maybe we want to try and remediate the issue automatically by executing a command or a script? This is where the so-called Actions come in. Actions are based on and/or conditions, that allow you to very granularly define how you’re going to react to a particular problem.

For example, you might define an action that states “If the Trigger name contains ‘SNMPSim’ send an email or a mobile text message to our Network administrator. If the problem still persists after 10 minutes, execute a locally stored script that should fix the problem.

Trigger actions

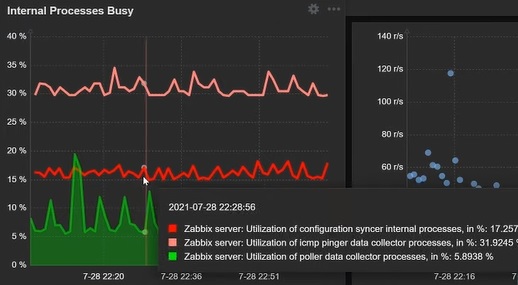
Once you have defined your items, triggers and actions, it’s time to present this information in a user-friendly fashion. For this, you can create a set of multi-page dashboards where you can see all of your collected data by utilizing different dashboard widgets together with a list of active problems,

display the collected metrics on graphs and provide an overview of your infrastructure state on network maps.

The dashboard is completely dynamic and interactive — you can zoom in on any point in time in your graphs, create interactive map hierarchies, navigate to different sections of Zabbix and much more.

Zabbix also supports SLA monitoring for your IT business services. You can define your IT service trees, link them to existing triggers and have access to different SLA related views.

Configuring and monitoring SLA

Inventory collection and storage is also natively supported by Zabbix. You can collect any inventory information from your devices – your device serial numbers, locations, software versions and much more. This can be done in many different ways – the inventory information can be captured from the collected metrics, populated manually or updated by using the Zabbix API. This information can be used to access different inventory views and group your devices based on the collected inventory data.

You own your data

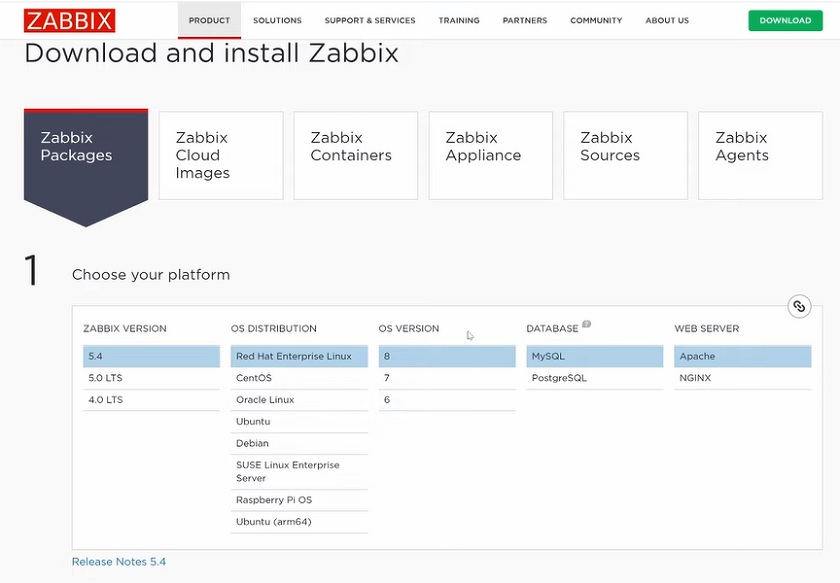
There are many different ways to deploy Zabbix. You can navigate to zabbix.com/download page and select the installation method that fits your requirements. For Zabbix packages you have the option to choose the required Zabbix version, select from multiple operating systems – from the Red Hat Enterprise Linux to Raspberry Pi, as well as the specific OS version, the database backend, and the web server backend. After everything is selected, you will be presented with a comprehensive list of commands that you can use to get Zabbix up and running in minutes.

Zabbix Packages

If you are interested in cloud deployments then you can also run Zabbix in many different cloud environments, such as AWS, Microsoft Azure, Google Cloud, DigitalOcean, Linode, Red Hat OpenShift, Oracle Cloud or Yandex Cloud. All of these options offer full Zabbix functionality with native cloud images.

Zabbix Cloud images

Docker images are also available for different Zabbix components. You can run a single component in a container or deploy the whole Zabbix architecture in a containerized environment. The Docker hub page contains a comprehensive list of environment variables and examples of how to deploy container images with a single command.


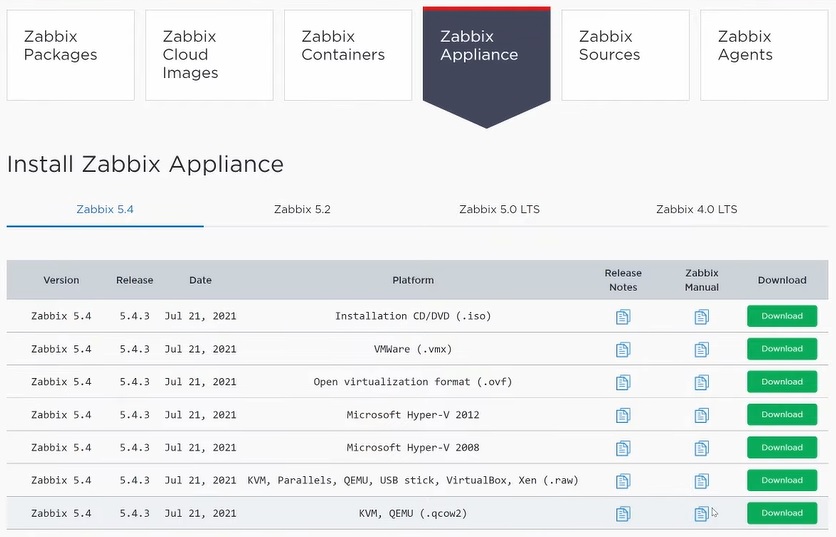
The quickest way to deploy Zabbix, especially in a PoC environment, would be the Zabbix Appliance. Zabbix Appliance is a virtual machine image with all of the Zabbix components already pre-configured for you. Simply download the image for the hypervisor of your choice, deploy it and you are good to go.


The Zabbix source code is also available for download for different Zabbix versions. This approach is useful for more exotic environments, where installing via packages is not an option.

Zabbix Sources

Agents are available for download via packages, but if packages is not an option, you can always download the precompiled agents for many different operating systems, including Windows.

Zabbix agents

No matter which option you choose, Zabbix LLC never has any access to your configuration or history data. You are fully in control of your deployment and the data in it. This way you have the guarantee that your data belongs only to you.

Balance of flexibility and simplicity

A good monitoring solution should be simple and approachable even for users that are not experts in monitoring, Linux system, scripting and any other DevOps-related skills. However, simplicity usually comes with at a cost of functionality. If the tool focuses too much on simplicity, it would inevitably restrict the end-users in the set of functionality that they have available for them.

Zabbix provides a balance of simplicity and flexibility. While the amount of features in Zabbix may seem daunting at first, the flexibility it provides is the key benefit of Zabbix. With Zabbix, you can easily extend the out-of-the-box monitoring approaches with your custom monitoring methods. If you have in-house applications specific to your company, you can always extend the Zabbix monitoring functionality and create your own custom checks or use scripts or commands to collect the data. This way you can define custom methods not only for data collection, but also use scripting for robust automatic issue remediation.

This gives you a huge variety of features that you can utilize in Zabbix either by using out-of-the-box templates or defining your own custom checks. All of this can be done within a single central frontend.

Even if you’re monitoring 50 branches in different countries within one Zabbix installation, a Zabbix administrator will be able to maintain and change the configuration — add new items, triggers, etc. Zabbix is also a great fit for multi-tenant environments. The robust permission and role schema enable you to define multiple Zabbix administrators that can have granular access to monitoring entities within their organization.

Commercial services

Open-source solutions are great as you can download the product at any time, irrespective of your goals and use them for both small home lab environments and large enterprise infrastructures. Similar to many open-source solutions, Zabbix also has a large and passionate international community of users ready to help you out on the official forums, different social networks, Zabbix subreddit and other communication channels.

If this not sufficient and you’re still feeling overwhelmed by all of the available features and require additional help to deploy your environment with best practices in mind – this is where the Zabbix commercial services come into play.

Commercial services

  • Zabbix team offers multiple commercial services, starting with a multiple-tier technical support. With technical support services, Zabbix experts will have your back and help you with fixing any issues and answer all of your questions 24/7.
  • Zabbix team also offers consulting services, where you can address any topic that you wish to discuss to Zabbix experts — how to deploy Zabbix and start monitoring your infrastructure, whether Zabbix is able to cover all of your needs, receive help with tuning Zabbix configuration and much more.
  • Turnkey solutions allow you to engage Zabbix professionals and build everything from scratch with best practices and scalability in mind.
  • Zabbix team can lend you a hand with Template building services for your custom in-house application.
  • The Zabbix team will document all of the performed steps, so you can have a clear view of what has been done and what was the reason behind it. You can utilize this knowledge down the line to learn and be able to follow the best practice approaches on your own.
  • Upgrade procedures can be extremely stressful – you may be worried about minimizing downtime, following your organizational SLA’s or maybe you simply aren’t sure how to properly perform an upgrade. Once again, the Zabbix team can do this for you, document it and guide you through the process so you can learn from it and do it yourself in the later versions.
  • Need help with troubleshooting an ongoing issue? Then the remote troubleshooting services are for you. Zabbix team can help you get to the bottom of any issues you may have with your Zabbix architecture.

Zabbix is an extremely fast-growing enterprise-ready project with a vast set of functionality trusted by global brands, capable to support collection of hundreds of thousands of metrics with real-time 24/7 data analysis, powerful visualization options, robust permission schema, out of the box reports and the ability to tailor the tool to your specific needs.

If you have never tried Zabbix, this might be the perfect moment to visit zabbix.com, click Download, and download Zabbix on your local test environment and try to monitor a couple of hosts to get acquainted with the product. I am sure that you’re going to be more than satisfied with the results!


CDK Corner – August 2021

Post Syndicated from Richard H Boyd original https://aws.amazon.com/blogs/devops/cdk-corner-august-2021/

We’re now well into the dog days of summer but that hasn’t slowed down the community one bit. In the past few months the team has delivered 3 big features that I think the community will love. The biggest new feature is the Construct Hub Developer Preview. Alex Pulver describes it as “a one-stop destination for finding, reusing, and sharing constructs”. The Construct Hub features constructs created by AWS, AWS Partner Network (APN) Partners, and the community. While the Construct Hub only includes TypeScript and Python constructs today, we will be adding support for the remaining jsii-supported languages in the coming months.

The next big release is the General Availability of CDK Pipelines. Instead of writing a new blog post for the General Availability launch, Rico updated the original announcement post to reflect updates made for GA. CDK Pipelines is a high-level construct library that makes it easy to set up a continuous deployment pipeline for your CDK-based applications. CDK Pipelines was announced last year and has seen several improvements, such as support for Docker registry credentials, cached builds, and getting started templates. To get started with your own CDK Pipelines, refer to the original launch blog post, that Rico has kindly updated for the GA announcement.

Since the launch of AWS CDK, customers have asked for a way to test their CDK constructs. The CDK assert library was previously only available for constructs written in TypeScript. With this new release, in which we have re-written the assert library to support jsii and renamed it the assertions library, customers can now test CDK constructs written in any supported language. The assertions library enables customers to test the generated AWS CloudFormation templates that a construct produces to ensure that the construct is designed and implemented properly. In June, Niranjan delivered an initial version of the assert library available in all supported languages. The RFC for “polyglot assert” describes the motivation fot this feature and some examples for using it.

Some key new constructs for AWS services include: – New L1 Constructs for AWS Location Services – New L2 Constructs for AWS CodeStar Connections – New L2 Constructs for Amazon CloudFront Functions – New L2 Constructs for AWS Service Catalog App Registry

This edition’s featured contribution comes from AWS Community Hero Philipp Garbe. Philipp added the ability to load Docker images from an existing tarball instead of rebuilding it from a Dockerfile.

Introducing public builds for AWS CodeBuild

Post Syndicated from Richard H Boyd original https://aws.amazon.com/blogs/devops/introducing-public-builds-for-aws-codebuild/

Using AWS CodeBuild, you can now share both the logs and the artifacts produced by CodeBuild projects. This blog post explains how to configure an existing CodeBuild project to enable public builds.

AWS CodeBuild is a fully managed continuous integration service that compiles source code, runs tests, and produces software packages that are ready to deploy. With CodeBuild, you don’t need to provision, manage, and scale your own build servers. With this new feature, you can now make the results of a CodeBuild project build publicly viewable. Public builds simplify the collaboration workflow for open source projects by allowing contributors to see the results of Continuous Integration (CI) tasks.

How public builds work

During a project build, CodeBuild will place build logs in either Amazon Simple Storage Service (Amazon S3) or Amazon CloudWatch, depending on how the customer has configured the project’s LogsConfig property. Optionally, a project build can produce artifacts that persist after the build has completed. During a project build that has public builds enabled, CodeBuild will set an environment variable named CODEBUILD_PUBLIC_BUILD_URL that supplies the URL for that build’s publicly viewable logs and artifacts. When a user navigates to that URL, CodeBuild will use an AWS Identity and Access Management (AWS IAM) Role (defined by the project maintainer) to fetch build logs and available artifacts and displays these.

To enable public builds for a project:

  1. Navigate to the resource page in the CodeBuild console for the project for which you want to enable public builds.
  2. In the Edit choose Project configuration.
  3. Select Enable public build access.
  4. Choose New service role.
  5. For Service role enter the role name you want this new role to have. For this post we will use the role name example-public-builds-role. This creates a new IAM role with the permissions defined in the next section of this blog post.
  6. Choose Update configuration to save the changes and return to the project’s resource page within the CodeBuild console.

Project builds will now have the build logs and artifacts made available at the URL listed in the Public project URL section of the Configuration panel within the project’s resource page.

Now the CI build statuses within pull requests for the GitHub repository will include a public link to the build results. When a pull request is created in the repository, CodeBuild will start a project build and provide commit status updates during the build with a link to the public build information. This link is available as a hyperlink from the Details section of the commit status message.

IAM role permissions

This new feature introduces a new IAM role for CodeBuild. The new role is assumed by the CodeBuild service and needs read access to the build logs and any potential artifacts you would like to make publicly available. In the previous example, we had configured the CodeBuild project to store logs in Amazon CloudWatch and placed our build artifacts in Amazon S3 (namespaced to the build ID). The following AWS CloudFormation template will create an IAM Role with the appropriate least-privilege policies for accessing the public build results.

Role template

Parameters:
  LogGroupName:
    Type: String
    Description: prefix for the CloudWatch log group name
  ArtifactBucketArn:
    Type: String
    Description: Arn for the Amazon S3 bucket used to store build artifacts.

Resources:
  PublicReadRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:
        Statement:
        - Action: ['sts:AssumeRole']
          Effect: Allow
          Principal:
            Service: [codebuild.amazonaws.com]
        Version: '2012-10-17'
      Path: /

  PublicReadPolicy:
    Type: 'AWS::IAM::Policy'
    Properties:
      PolicyName: PublicBuildPolicy
      PolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Action:
              - "logs:GetLogEvents"
            Resource:
              - !Sub "arn:aws:logs:${AWS::Region}:${AWS::AccountId}:log-group:${LogGroupName}:*"
          - Effect: Allow
            Action:
              - "s3:GetObject"
              - "s3:GetObjectVersion"
            Resource:
              - !Sub "${ArtifactBucketArn}/*"
      Roles:
        - !Ref PublicReadRole

Creating a public build in AWS CloudFormation

Using AWS CloudFormation, you can provision CodeBuild projects using infrastructure as code (IaC). To update an existing CodeBuild project to enable public builds add the following two fields to your project definition:

  CodeBuildProject:
    Type: AWS::CodeBuild::Project
    Properties:
      ServiceRole: !GetAtt CodeBuildRole.Arn
      LogsConfig: 
        CloudWatchLogs:
          GroupName: !Ref LogGroupName
          Status: ENABLED
          StreamName: ServerlessRust
      Artifacts:
        Type: S3
        Location: !Ref ArtifactBucket
        Name: ServerlessRust
        NamespaceType: BUILD_ID
        Packaging: ZIP
      Environment:
        Type: LINUX_CONTAINER
        ComputeType: BUILD_GENERAL1_LARGE
        Image: aws/codebuild/standard:4.0
        PrivilegedMode: true
      Triggers:
        BuildType: BUILD
        Webhook: true
        FilterGroups:
          - - Type: EVENT
              Pattern: PULL_REQUEST_CREATED,PULL_REQUEST_UPDATED
      Source:
        Type: GITHUB
        Location: "https://github.com/richardhboyd/ServerlessRust.git"
        BuildSpec: |
          version: 0.2
          phases:
            build:
              commands:
                - sam build
          artifacts:
            files:
              - .aws-sam/build/**/*
            discard-paths: no
      Visibility: PUBLIC_READ
      ResourceAccessRole: !Ref PublicReadRole # Note that this references the role defined in the previous section.
 

Disabling public builds

If a project has public builds enabled and you would like to disable it, you can clear the check-box named Enable public build access in the project configuration or set the Visibility to PRIVATE in the CloudFormation definition for the project. To prevent any project in your AWS account from using public builds, you can set an AWS Organizations service control policy (SCP) to deny the IAM Action CodeBuild:UpdateProjectVisibility

Conclusion

With CodeBuild public builds, you can now share build information for your open source projects with all contributors without having to grant them direct access to your AWS account. This post explains how to enable public builds with AWS CodeBuild using both the console and CloudFormation, create a least-privilege IAM role for sharing the public build results, and how to disable public builds for a project.

Adding support for cross-cluster associations to Rails 7

Post Syndicated from Eileen M. Uchitelle original https://github.blog/2021-07-12-adding-support-cross-cluster-associations-rails-7/

Ever since we made the leap at GitHub to upgrade off our fork of Rails and worked hard to stay up to date with the latest releases, we’ve consistently looked for ways to improve the Rails framework upstream. We do this in many ways – running GitHub off of Rails main, reporting and fixing bugs we find, and most importantly pushing functionality upstream that the entire Ruby community can benefit from.

Most recently, we extracted internal functionality to disable joining queries when an association crossed multiple databases. Prior to our work in this area, Rails had no support for handling associations that spanned across clusters; teams had to write SQL to achieve this.

Background

At GitHub, we have 30 databases configured in our Rails monolith—15 primaries and 15 replicas. We use “functional partitioning” to split up our data, which means that each of those 15 primaries has a different schema. In contrast, a “horizontal sharding” approach would have 15 shards with the same schema.

While there are some workarounds for joining across clusters in MySQL, they are usually not performant or else they require additional setup. Without these workarounds, attempting to join from a table in cluster A to a table in cluster B would result in an error. To work around this limitation, teams had to write SQL, selecting IDs from the first table to then use in the second query to find the appropriate records. This was extra work and could be error-prone. We had an opportunity to make this process smoother by implementing non-join queries in Rails.

Let’s look at some code to see how this works:

Let’s say we have three models: Dog, Human, and Treat.

# table dogs in database animals
class Dog < AnimalsRecord  
  has_many: treats, through: :humans
  has_many :humans
end

# table humans in database people
class Human < PeopleRecord
  has_many :treats
  has_many :dogs
end

# table treats in database default
class Treat < ApplicationRecord
  has_many :dogs, through: :humans
  has_many :humans
end

If our Rails application code loaded the dog.treats association, usually that would automatically perform a join query:

SELECT treats.* FROM treats INNER JOIN humans ON treats.human_id = humans.id WHERE humans.dog_id = 2

Looking at the inheritance chain, we can see that Dog, Treat, and Human all inherit from different base classes. Each of these base classes belongs to a different database connection, which means that records for all three models are stored in different databases.

Since the data is stored across multiple primaries, when the join on dog.treats is run we’ll see an application error:

ActiveRecord::StatementInvalid (Table 'people_db_cluster.humans' doesn't exist)

One of the best features Rails provides out of the box is generating SQL for you. But since GitHub’s data lives in different databases, we could no longer take advantage of this. We had an opportunity to improve Rails in a way that benefited our engineers and everyone else in the Rails community who uses multiple databases.

Implementation

Prior to our work in this area, engineers working on any associations that crossed database boundaries would be forced to manually query IDs rather than using Active Record’s association APIs. Writing SQL can be error prone and defeats the purpose of Active Record’s convenience methods like dog.treats.

A little over two years ago, we started experimenting with an internal gem to disable joins for cross-database associations. We chose to implement this outside of Rails first so that we could work out the majority of bugs before merging to Rails. We wanted to be sure that we could use it successfully in production and that it didn’t cause any significant friction in development or any performance concerns in production. This is how many of Rails’ popular features get developed. We often extract implementations from large production applications – if it’s something we need and something a lot of applications can benefit from, we make it stable first, then upstream it to Rails.

The overall implementation is relatively small. To accomplish disabling joins, we added an option to has_many :through associations called disable_joins. When set to true for an association, Rails will generate separate queries for each database rather than a join query.

This needed to be an option on the association rather than performed at runtime because Rails associations are lazily loaded – the SQL is generated when the association objects are created, which means that by the time Rails runs the SQL to load dog.treats the join will already be generated. After adding the option in Rails, we implemented a new scoping class that would handle the order, limit, scopes, and other options.

Now applications can add the following to their associations to make sure Rails generates two or more queries instead of joins:

class Dog < AnimalsRecord
  has_many: treats, through: :humans, disable_joins: true
  has_many :humans
end

And that’s all that’s needed to disable generating joins for associations that cross database servers!

Now, calls to dog.treats will generate the following SQL:

SELECT "humans"."id" FROM "humans" WHERE "humans"."dog_id" = ?  [["dog_id", 1]]
SELECT "treats".* FROM "treats" WHERE "treats"."human_id" IN (?, ?, ?)  [["human_id", 1], ["human_id", 2], ["human_id", 3]]

Caveats

There are a couple of important caveats to keep in mind when using this new feature. Applications that need to disable joins may see that those associations have slower database performance. This would be true whether you wrote the SQL manually or use Rails’ new disable_joins feature. Fundamentally, if you’re performing multiple queries across multiple databases, that can be slower than performing a single join query on one database. It’s really important to make sure that your queries are efficient and that proper indexes are in place before using this feature. And as always, when making major changes to your database queries, it’s important to benchmark and understand how those changes will affect your application.

Additionally, if your queries rely on an order and limit from the join database you may see a performance impact on requests. When two queries are joined, MySQL can perform the order based on the table that’s joined (i.e., order by humans.human_id which would order the returned treats by the human ID). However, when you’re splitting queries the order can’t be applied by the database. To solve this, Rails orders the records in-memory based on the order they would have been returned if there was a join. This preserves the expected behavior but since the order and limit are performed in-memory, you’ll usually want to avoid performing these actions on hundreds of thousands of records.

Conclusion

Four years ago, contributing to Rails at this level was just something we’d hoped to be able to do one day. We were so far behind in our upgrades that it was difficult to contribute changes to the framework. This might look like a small change but it’s a clear demonstration of the hard work we’ve done to improve the technical debt in our application and ensure that we’re giving back to the community whenever we can.

By adding support for handling associations across databases, we help empower other applications to scale as their traffic and data grow. Additionally, by pushing this code into Rails and out of our private internal gem we’ll find even more improvements and edge cases in applications that aren’t GitHub. As we continue to grow and improve Rails for us at GitHub, we’ll continue to improve it for the entire community. This pull request is just one example of how we intend to do that for years to come.

Choosing a Well-Architected CI/CD approach: Open-source software and AWS Services

Post Syndicated from Brian Carlson original https://aws.amazon.com/blogs/devops/choosing-well-architected-ci-cd-open-source-software-aws-services/

This series of posts discusses making informed decisions when choosing to implement open-source tools on AWS services, adopt managed AWS services to satisfy the same needs, or use a combination of both.

We look at key considerations for evaluating open-source software and AWS services using the perspectives of a startup company and a mature company as examples. You can use these two different points of view to compare to your own organization. To make this investigation easier we will use Continuous Integration (CI) and Continuous Delivery (CD) capabilities as the target of our investigation.

Startup Company rocket and Mature Company rocket

In two related posts, we follow two AWS customers, Iponweb and BigHat Biosciences, as they share their CI/CD journeys, their perspectives, the decisions they made, and why. To end the series, we explore an example reference architecture showing the benefits AWS provides regardless of your emphasis on open-source tools or managed AWS services.

Why CI/CD?

Until your creations are in the hands of your customers, investment in development has provided no return. The faster valuable changes enter production, the greater positive impact you can have on your customer. In today’s highly competitive world, the ability to frequently and consistently deliver value is a competitive advantage. The Operational Excellence (OE) pillar of the AWS Well-Architected Framework recognizes this impact and focuses on the capabilities of CI/CD in two dedicated sections.

The concepts in CI/CD originate from software engineering but apply equally to any form of content. The goal is to support development, integration, testing, deployment, and delivery to production. For example, making changes to an application, updating your machine learning (ML) models, changing your multimedia assets, or referring to the AWS Well-Architected Framework.

Adopting CI/CD and the best practices from the Operational Excellence pillar can help you address risks in your environment, and limit errors from manual processes. More importantly, they help free your teams from the related manual processes, so they can focus on satisfying customer needs, differentiating your organization, and accelerating the flow of valuable changes into production.

A red question mark sits on a field of chaotically arranged black question marks.

How do you decide what you need?

The first question in the Operational Excellence pillar is about understanding needs and making informed decisions. To help you frame your own decision-making process, we explore key considerations from the perspective of a fictional startup company and a fictional mature company. In our two related posts, we explore these same considerations with Iponweb and BigHat.

The key considerations include:

  • Functional requirements – Providing specific features and capabilities that deliver value to your customers.
  • Non-functional requirements – Enabling the safe, effective, and efficient delivery of the functional requirements. Non-functional requirements include security, reliability, performance, and cost requirements.
    • Without security, you can’t earn customer trust. If your customers can’t trust you, you won’t have customers.
    • Without reliability you aren’t available to serve your customers. If you can’t serve your customers, you won’t have customers.
    • Performance is focused on timely and efficient delivery of value, not delivering as fast as possible.
    • Cost is focused on optimizing the value received for the resources spent (for example, money, time, or effort), not minimizing expense.
  • Operational requirements – Enabling you to effectively and efficiently support, maintain, sustain, and improve the delivery of value to your customers. When you “Design with Ops in Mind,” you’re enabling effective and efficient support for your business outcomes.

These non-feature-related key considerations are why Operational Excellence, Security, Reliability, Performance Efficiency, and Cost Optimization are the five pillars of the AWS Well-Architected Framework.

The startup company

Any startup begins as a small team of inspired people working together to realize the unique solution they believe solves an unsolved problem.

For our fictional small team, everyone knows each other personally and all speak frequently. We share processes and procedures in discussions, and everyone know what needs to be done. Our team members bring their expertise and dedicate it, and the majority of their work time, to delivering our solution. The results of our efforts inform changes we make to support our next iteration.

However, our manual activities are error-prone and inconsistencies exist in the way we do them. Performing these tasks takes time away from delivering our solution. When errors occur, they have the potential to disrupt everyone’s progress.

We have capital available to make some investments. We would prefer to bring in more team members who can contribute directly to developing our solution. We need to iterate faster if we are to achieve a broadly viable product in time to qualify for our next round of funding. We need to decide what investments to make.

  • Goals – Reach the next milestone and secure funding to continue development
  • Needs – Reduce or eliminate the manual processes and associated errors
  • Priority – Rapid iteration
  • CI/CD emphasis – Baseline CI/CD capabilities and non-functional requirements are emphasized over a rich feature set

The mature company

Our second fictional company is a large and mature organization operating in a mature market segment. We’re focused on consistent, quality customer experiences to serve and retain our customers.

Our size limits the personal relationships between our service and development teams. The process to make requests, and the interfaces between teams and their systems, are well documented and understood.

However, the systems we have implemented over time, as needs were identified and addressed, aren’t well documented. Our existing tool chain includes some in-house scripting and both supported and unsupported versions of open-source tools. There are limited opportunities for us to acquire new customers.

When conditions change and new features are desired, we want to be able to rapidly implement and deploy those features as fast as possible. If we can differentiate our services, however briefly, we may be able to win customers away from our competitors. Our other path to improved profitability is to evolve our processes, maximizing integration and efficiencies, and capturing cost reductions.

  • Goals – Differentiate ourselves in the marketplace with desired new features
  • Needs – Address the risks of poorly documented systems and unsupported software
  • Priority – Evolve efficiency
  • CI/CD emphasis – Rich feature set and integrations are emphasized over improving the existing non-functional capabilities

Open-source tools on AWS vs. AWS services

The choice of open-source tools or AWS service is not binary. You can select the combination of solutions that provides the greatest value. You can implement open-source tools for their specific benefits where they outweigh the costs and operational burden, using underlying AWS services like Amazon Elastic Compute Cloud (Amazon EC2) to host them. You can then use AWS managed services, like AWS CodeBuild, for the undifferentiated features you need, without additional cost or operational burden.

A group of people sit around a table discussing the pieces of a puzzle and their ideas.

Feature Set

Our fictional organizations both want to accelerate the flow of beneficial changes into production and are evaluating CI/CD alternatives to support that outcome. Our startup company wants a working solution—basic capabilities, author/code, build, and deploy, so that they can focus on development. Our mature company is seeking every advantage—a rich feature set, extensive opportunities for customization, integration capabilities, and fine-grained control.

Open-source tools

Open-source tools often excel at meeting functional requirements. When a new functionality, capability, or integration is desired, any developer can implement it for themselves, and then contribute their code back to the project. As the user community for an open-source project expands the number of use cases and the features identified grows, so does the number of potential solutions and potential contributors. Developers are using these tools to support their efforts and implement new features that provide value to them.

However, features may be released in unsupported versions and then later added to the supported feature set. Non-functional requirements take time and are less appealing because they don’t typically bring immediate value to the product. Non-functional capabilities may lag behind the feature set.

Consider the following:

  • Open-source tools may have more features and existing integrations to other tools
  • The pace of feature set delivery may be extremely rapid
  • The features delivered are those desired and created by the active members of the community
  • You are free to implement the features your company desires
  • There is no commitment to long-term support for the project or any given feature
  • You can implement open-source tools on multiple cloud providers or on premises
  • If the project is abandoned, you’re responsible for maintaining your implementation

AWS services

AWS services are driven by customer needs. Services and features are supported by dedicated teams. These customer-obsessed teams focus on all customer needs, with security being their top priority. Both functional and non-functional requirements are addressed with an emphasis on enabling customer outcomes while minimizing the effort they expend to achieve them.

Consider the following:

  • The pace of delivery of feature sets is consistent
  • The feature roadmap is driven by customer need and customer requests
  • The AWS service team is dedicated to support of the service
  • AWS services are available on the AWS Cloud and on premises through AWS Outposts

Picture showing symbol of dollar

Cost Optimization

Why are we discussing cost after the feature set? Security and reliability are fundamentally more important. Leadership naturally gravitates to following the operational excellence best practice of evaluating trade-offs. Having looked at the potential benefits from the feature set, the next question is typically, “What is this going to cost?” Leadership defines the priorities and allocates the resources necessary (capital, time, effort). We review cost optimization second so that leadership can make a comparison of the expected benefits between CI/CD investments, and investments in other efforts, so they can make an informed decision.

Our organizations are both cost conscious. Our startup is working with finite capital and time. In contrast, our mature company can plan to make investments over time and budget for the needed capital. Early investment in a robust and feature-rich CI/CD tool chain could provide significant advantages towards the startup’s long-term success, but if the startup fails early, the value of that investment will never be realized. The mature company can afford to realize the value of their investment over time and can make targeted investments to address specific short-term needs.

Open-source tools

Open-source software doesn’t have to be purchased, but there are costs to adopt. Open-source tools require appropriate skills in order to be implemented, and to perform management and maintenance activities. Those skills must be gained through dedicated training of team members, team member self-study, or by hiring new team members with the existing skills. The availability of skilled practitioners of open-source tools varies with how popular a tool is and how long it has had an active community. Loss of skilled team members includes the loss of their institutional knowledge and intimacy with the implementation. Skills must be maintained with changes to the tools and as team members join or leave. Time is required from skilled team members to support management and maintenance activities. If commercial support for the tool is desired, it may be available through third-parties at an additional cost.

The time to value of an open-source implementation includes the time to implement and configure the resources and software. Additional value may be realized through investment of time configuring or implementing desired integrations and capabilities. There may be existing community-supported integrations or capabilities that reduce the level of effort to achieve these.

Consider the following:

  • No cost to acquire the software.
  • The availability of skill practitioners of open-source tools may be lower. Cost (capital and time) to acquire, establish, or maintain skill set may be higher.
  • There is an ongoing cost to maintain the team member skills necessary to support the open-source tools.
  • There is an ongoing cost of time for team members to perform management and maintenance activities.
  • Additional commercial support for open-source tools may be available at additional cost
  • Time to value includes implementation and configuration of resources and the open-source software. There may be more predefined community integrations.

AWS services

AWS services are provided pay-as-you-go with no required upfront costs. As of August 2020, more than 400,000 individuals hold active AWS Certifications, a number that grew more than 85% between August 2019 and August 2020.

Time to value for AWS services is extremely short and limited to the time to instantiate or configure the service for your use. Additional value may be realized through the investment of time configuring or implementing desired integrations. Predefined integrations for AWS services are added as part of the service development roadmap. However, there may be fewer existing integrations to reduce your level of effort.

Consider the following:

  • No cost to acquire the software; AWS services are pay-as-you-go for use.
  • AWS skill sets are broadly available. Cost (capital and time) to acquire, establish, or maintain skill sets may be lower.
  • AWS services are fully managed, and service teams are responsible for the operation of the services.
  • Time to value is limited to the time to instantiate or configure the service. There may be fewer predefined integrations.
  • Additional support for AWS services is available through AWS Support. Cost for support varies based on level of support and your AWS utilization.

Open-source tools on AWS services

Open-source tools on AWS services don’t impact these cost considerations. Migration off of either of these solutions is similarly not differentiated. In either case, you have to invest time in replacing the integrations and customizations you wish to maintain.

Picture showing a checkmark put on security

Security

Both organizations are concerned about reputation and customer trust. They both want to act to protect their information systems and are focusing on confidentiality and integrity of data. They both take security very seriously. Our startup wants to be secure by default and wants to trust the vendor to address vulnerabilities within the service. Our mature company has dedicated resources that focus on security, and the company practices defense in depth across internal organizations.

The startup and the mature company both want to know whether a choice is safe, secure, and can validate the security of their choice. They also want to understand their responsibilities and the shared responsibility model that applies.

Open-source tools

Open-source tools are the product of the contributors and may contain flaws or vulnerabilities. The entire community has access to the code to test and validate. There are frequently many eyes evaluating the security of the tools. A company or individual may perform a validation for themselves. However, there may be limited guidance on secure configurations. Controls in the implementer’s environment may reduce potential risk.

Consider the following:

  • You’re responsible for the security of the open-source software you implement
  • You control the security of your data within your open-source implementation
  • You can validate the security of the code and act as desired

AWS services

AWS service teams make security their highest priority and are able to respond rapidly when flaws are identified. There is robust guidance provided to support configuring AWS services securely.

Consider the following:

  • AWS is responsible for the security of the cloud and the underlying services
  • You are responsible for the security of your data in the cloud and how you configure AWS services
  • You must rely on the AWS service team to validate the security of the code

Open-source tools on AWS services

Open-source tools on AWS services combine these considerations; the customer is responsible for the open-source implementation and the configuration of the AWS services it consumes. AWS is responsible for the security of the AWS Cloud and the managed AWS services.

Picture showing global distribution for redundancy to depict reliability

Reliability

Everyone wants reliable capabilities. What varies between companies is their appetite for risk, and how much they can tolerate the impact of non-availability. The startup emphasized the need for their systems to be available to support their rapid iterations. The mature company is operating with some existing reliability risks, including unsupported open-source tools and in-house scripts.

The startup and the mature company both want to understand the expected reliability of a choice, meaning what percentage of the time it is expected to be available. They both want to know if a choice is designed for high availability and will remain available even if a portion of the systems fails or is in a degraded state. They both want to understand the durability of their data, how to perform backups of their data, and how to perform recovery in the event of a failure.

Both companies need to determine what is an acceptable outage duration, commonly referred to as a Recovery Time Objective (RTO), and for what quantity of elapsed time it is acceptable to lose transactions (including committing changes), commonly referred to as Recovery Point Objective (RPO). They need to evaluate if they can achieve their RTO and RPO objectives with each of the choices they are considering.

Open-source tools

Open-source reliability is dependent upon the effectiveness of the company’s implementation, the underlying resources supporting the implementation, and the reliability of the open-source software. Open-source tools are the product of the contributors and may or may not incorporate high availability features. Depending on the implementation and tool, there may be a requirement for downtime for specific management or maintenance activities. The ability to support RTO and RPO depends on the teams supporting the company system, the implementation, and the mechanisms implemented for backup and recovery.

Consider the following:

  • You are responsible for implementing your open-source software to satisfy your reliability needs and high availability needs
  • Open-source tools may have downtime requirements to support specific management or maintenance activities
  • You are responsible for defining, implementing, and testing the backup and recovery mechanisms and procedures
  • You are responsible for the satisfaction of your RTO and RPO in the event of a failure of your open-source system

AWS services

AWS services are designed to support customer availability needs. As managed services, the service teams are responsible for maintaining the health of the services.

Consider the following:

Open-source tools on AWS services

Open-source tools on AWS services combine these considerations; the customer is responsible for the open-source implementation (including data durability, backup, and recovery) and the configuration of the AWS services it consumes. AWS is responsible for the health of the AWS Cloud and the managed services.

Picture showing a graph depicting performance measurement

Performance

What defines timely and efficient delivery of value varies between our two companies. Each is looking for results before an engineer becomes idled by having to wait for results. The startup iterates rapidly based on the results of each prior iteration. There is limited other activity for our startup engineer to perform before they have to wait on actionable results. Our mature company is more likely to have an outstanding backlog or improvements that can be acted upon while changes moves through the pipeline.

Open-source tools

Open-source performance is defined by the resources upon which it is deployed. Open-source tools that can scale out can dynamically improve their performance when resource constrained. Performance can also be improved by scaling up, which is required when performance is constrained by resources and scaling out isn’t supported. The performance of open-source tools may be constrained by characteristics of how they were implemented in code or the libraries they use. If this is the case, the code is available for community or implementer-created improvements to address the limitation.

Consider the following:

  • You are responsible for managing the performance of your open-source tools
  • The performance of open-source tools may be constrained by the resources they are implemented upon; the code and libraries used; their system, resource, and software configuration; and the code and libraries present within the tools

AWS services

AWS services are designed to be highly scalable. CodeCommit has a highly scalable architecture, and CodeBuild scales up and down dynamically to meet your build volume. CodePipeline allows you to run actions in parallel in order to increase your workflow speeds.

Consider the following:

  • AWS services are fully managed, and service teams are responsible for the performance of the services.
  • AWS services are designed to scale automatically.
  • Your configuration of the services you consume can affect the performance of those services.
  • AWS services quotas exist to prevent unexpected costs. You can make changes to service quotas that may affect performance and costs.

Open-source tools on AWS services

Open-source tools on AWS services combine these considerations; the customer is responsible for the open-source implementation (including the selection and configuration of the AWS Cloud resources) and the configuration of the AWS services it consumes. AWS is responsible for the performance of the AWS Cloud and the managed AWS services.

Picture showing cart-wheels in motion, depicting operations

Operations

Our startup company wants to limit its operations burden as much as possible in order to focus on development efforts. Our mature company has an established and robust operations capability. In both cases, they perform the management and maintenance activities necessary to support their needs.

Open-source tools

Open-source tools are supported by their volunteer communities. That support is voluntary, without any obligation or commitment from the users. If either company adopts open-source tools, they’re responsible for the management and maintenance of the system. If they want additional support with an obligation and commitment to support their implementation, third parties may provide commercial support at additional cost.

Consider the following:

  • You are responsible for supporting your implementation.
  • The open-source community may provide volunteer support for the software.
  • There is no commitment to support the software by the open-source community.
  • There may be less documentation, or accepted best practices, available to support open-source tools.
  • Early adoption of open-source tools, or the use of development builds, includes the chance of encountering unidentified edge cases and unanticipated issues.
  • The complexity of an implementation and its integrations may increase the difficulty to support open-source tools. The time to identify contributing factors may be extended by the complexity during an incident. Maintaining a set of skilled team members with deep understanding of your implementation may help mitigate this risk.
  • You may be able to acquire commercial support through a third party.

AWS services

AWS services are committed to providing long-term support for their customers.

Consider the following:

  • There is long-term commitment from AWS to support the service
  • As a managed service, the service team maintains current documentation
  • Additional levels of support are available through AWS Support
  • Support for AWS is available through partners and third parties

Open-source tools on AWS services

Open-source tools on AWS services combine these considerations. The company is responsible for operating the open-source tools (for example, software configuration changes, updates, patching, and responding to faults). AWS is responsible for the operation of the AWS Cloud and the managed AWS services.

Conclusion

In this post, we discussed how to make informed decisions when choosing to implement open-source tools on AWS services, adopt managed AWS services, or use a combination of both. To do so, you must examine your organization and evaluate the benefits and risks.

A magnifying glass is focused on the single red figure in a group of otherwise blue paper figures standing on a white surface.

Examine your organization

You can make an informed decision about the capabilities you adopt. The insight you need can be gained by examining your organization to identify your goals, needs, and priorities, and discovering what your current emphasis is. Ask the following questions:

  • What is your organization trying to accomplish and why?
  • How large is your organization and how is it structured?
  • How are roles and responsibilities distributed across teams?
  • How well defined and understood are your processes and procedures?
  • How do you manage development, testing, delivery, and deployment today?
  • What are the major challenges your organization faces?
  • What are the challenges you face managing development?
  • What problems are you trying to solve with CI/CD tools?
  • What do you want to achieve with CI/CD tools?

Evaluate benefits and risk

Armed with that knowledge, the next step is to explore the trade-offs between open-source options and managed AWS services. Then evaluate the benefits and risks in terms of the key considerations:

  • Features
  • Cost
  • Security
  • Reliability
  • Performance
  • Operations

When asked “What is the correct answer?” the answer should never be “It depends.” We need to change the question to “What is our use case and what are our needs?” The answer will emerge from there.

Make an informed decision

A Well-Architected solution can include open-source tools, AWS Services, or any combination of both! A Well-Architected choice is an informed decision that evaluates trade-offs, balances benefits and risks, satisfies your requirements, and most importantly supports the achievement of your business outcomes.

Read the other posts in this series and take this journey with BigHat Biosciences and Iponweb as they share their perspectives, the decisions they made, and why.

Resources

Want to learn more? Check out the following CI/CD and developer tools on AWS:

Continuous integration (CI)
Continuous delivery (CD)
AWS Developer Tools

For more information about the AWS Well-Architected Framework, refer to the following whitepapers:

AWS Well-Architected Framework
AWS Well-Architected Operational Excellence pillar
AWS Well-Architected Security pillar
AWS Well-Architected Reliability pillar
AWS Well-Architected Performance Efficiency pillar
AWS Well-Architected Cost Optimization pillar

The 3 hexagons of the well architected logo appear to the right of the words AWS Well-Architected.

Author bio

portrait photo of Brian Carlson Brian is the global Operational Excellence lead for the AWS Well-Architected program. Formerly the technical lead for an international network, Brian works with customers and partners researching the operations best practices with the greatest positive impact and produces guidance to help you achieve your goals.


GitHub Artifact Exporter open source release

Post Syndicated from Jason Macgowan original https://github.blog/2021-05-18-github-artifact-exporter-open-source-release/

GitHub is the home for software development teams and is the place where they collaborate and build. For larger organizations, you might have a dedicated reporting team that wants to export this activity at a granular level, so it can be modified and presented for audits. GitHub provides a powerful API for accessing this data programmatically, but we know that may not be the perfect solution for the many people involved in a given organization. In fact, a common request we’ve seen is for the ability to download issues and other repository data as a CSV file. Sometimes, you just want a spreadsheet!

So, we built the GitHub Artifact Exporter to help reporting teams get the data they need without requiring them to know how to interact with the GitHub API.

What data can you export from GitHub?

GitHub Artifact Exporter provides a CLI and a simple GUI for exporting GitHub Issues and related comments based on a date range, and it supports GitHub’s full search syntax, allowing you to filter results based on your search parameters

The CLI also supports exporting:

  • Commits
  • Milestones, including associated Issues
  • Projects, including associated issues
  • Pull requests, including comments
  • Releases

Exporter format

Both the CLI and GUI support two formats for data exports, JSON and CSV.

JSON

Newline delimited JSON can be used to process each line.

Screenshot of JSON data export using GitHub Artifact Exporter

CSV

CSV provides a comma-delimited export where each line represents an issue and a single comment.

Screenshot of comma-delimited CSV data export using GitHub Artifact Exporter

Using the GUI

When you open the GUI, you’re greeted with the screen below. You’ll need to fill in a personal access token, the owner of the repository, and the name of the repository itself.

The owner of the repository will either be your personal account name or your organization name. The name of the repository will be the URL slug that you see in the URL bar. The GitHub Artifact Exporter’s Owner and Repository would be “github” and “github-artifact-exporter” respectively.

Next, input a search string to filter the issues in your repository, select whether you want CSV or JSON output, and hit export! You’ll be prompted with a dialogue allowing you to choose the location to save the file.

Screenshot of GUI for GitHub Artifact Exporter, showing the fields described above.

Using the CLI

The CLI can be used to generate the same JSON and CSV data as the GUI, in addition to implementing a handful of other search types. See the usage portion of the README for full details.

For example, to get all the pull requests in your repository, this command could be used:
github-artifact-exporter.exe repo:pulls --owner github --repo github-artifact-exporter --token $GITHUB_TOKEN --format JSON.

Try it out!

We hope that this tool helps your team export your data in an easier fashion. To get started, check out the prerequisites then download the GitHub Artifact Exporter. We would love any suggestions or feedback in the repository.

Scaling monorepo maintenance

Post Syndicated from Taylor Blau original https://github.blog/2021-04-29-scaling-monorepo-maintenance/

At GitHub, we serve some of the largest Git repositories on the planet. We also serve some of the fastest-growing repositories. Each day, the largest repositories we host become even larger.

About a year ago, we noticed that the job we use to repack Git repositories began hitting our self-imposed timeouts on larger repositories. Even when expanding these timeouts, failing maintenance on these repositories has generally been the cause of degraded performance that is hard to mitigate.

Today, these problems do not exist. GitHub can repack even the largest repositories we host in a fraction of the time it used to take. In this post, we’ll talk about what problems we were encountering, the solutions we built, how we deployed them safely, and describe some possible future directions.

All of our work here is being contributed to the open source Git project, and will be available in an upcoming release.

The problem

Why is GitHub’s maintenance job so expensive in the first place? It’s because we chose to have maintenance repack the entire contents of each repository into a single packfile. Doing so is expensive, but having just one packfile carries some benefits, too. With only one packfile, looking up objects doesn’t require opening and searching through multiple packs to find it. It also means that all objects can be compressed as a delta relative to all other objects (Git’s packfile format supports cross-pack deltas, but currently Git will never store them on disk). But, the most important reason is that reachability bitmaps, a performance-critical data structure, are only compatible with a single pack.

A new feature in Git, multi-pack indexes solves the former problem by making all object lookups go through a single index, but didn’t yet solve the latter. So, we set out to fill in the gaps by bringing bitmap support to multi-pack indexes in order to remove the single-pack limitation on reachability bitmaps.

But in order to build multi-pack bitmaps, we had to solve a number of other interesting problems along the way. First, we had to decide how to arrange the objects in a multi-pack index to achieve good bitmap compression. We also had to figure out how to quickly invert that ordering to translate between bit positions back to the objects they refer to. Some of these steps also yielded notable performance improvements on single-pack repositories, too. Finally, we had to figure out a new repacking strategy that scaled with the size of recent pushes, rather than with the size of the entire repository.

But before we get into all of that, let’s start from the very beginning.

Objects, packs, and fetching

You might be aware that Git stores the contents of your repositories as a set of objects. Each object represents an individual piece of your repository: a single file, tree, commit, or tag. These objects may be stored individually as “loose” objects, or together in a packfile.

If you’ve ever heard that a Git repository is “nothing more than a directed acyclic graph,” then you know that these objects can refer to one another. A tree refers to a set of blobs (which correspond to files) and other trees (which correspond to sub-directories). A commit refers to a single tree (the repository root), and zero or more other commits which are its parents.

These links help Git figure out which objects it needs to transfer to fulfill a fetch or clone request. When you fetch a repository from GitHub, Git performs a negotiation to figure out which objects to send. The server advertises the objects at the tip of its references (basically the tips of branches and tags). The client does the same, along with the set of references that it wants from the server. Then, the server walks the links between the requested objects and the objects that the client already has in order to figure out what to send.

Above is an object graph. The client advertises its ref tips (indicated by the darker blue commits). The server’s advertised references are colored dark red. The blue shaded area represents the result of walking along the edges to obtain the reachability closure of the objects the client already has. The red shaded area represents the same closure from the server’s perspective, excluding objects that the client already has. Objects in this region are the ones which need to be sent to the client.

During a fetch, Git needs to send not just the commits in between what the client has and wants, but also all of the objects that are reachable from those commits. Because Git doesn’t store the list of every reachable object, this may be expensive, especially in the case of a clone. When cloning, the client doesn’t have any objects, so it asks the server for all of the objects reachable from any reference.

In an earlier blog post, we talked about how we use reachability bitmaps to accelerate this negotiation. In case you haven’t read that post, below is a quick primer.

Reachability bitmaps

How does Git handle this special case where the client has nothing and wants everything? Ultimately, the server needs to determine the reachability closure of all of the reference tips. In other words, it needs a list of all of the objects at the reference tips, and all of the ancestors of those objects in order to assemble a complete copy of the repository at the other end.

Unfortunately for us, the larger the repository is, the longer it takes Git to compute the list of objects to send. This isn’t feasible even for medium-sized repositories. Git could handle our case specially by just sending every object it has, but that might result in many unwanted objects being sent, too. (For example, GitHub stores the outcome of “test merges” in special refs which aren’t ordinarily sent during fetches, but whose objects are stored in the same object directory nonetheless.)

Instead, Git stores a set of reachability bitmaps corresponding to some of the commits in a packfile. The idea is rather simple: arrange the objects in a pack in some order (the particular order used is something we’ll discuss shortly in detail). Then, the ith bit in the bitmap corresponding to commit C is 1 if C can reach the ith object, and 0 otherwise.

Having a one-to-one correspondence between objects and bit positions has a couple of appealing properties: taking the union of reachable objects between commits is as simple as ORing their bitmaps together, and taking the difference is as simple as combining AND and NOT. So, when a bitmap exists, Git can dramatically speed up the object negotiation phase:

  • First, OR all of the bitmaps corresponding to the reference tips that the client wants. Call this new bitmap W.
  • Then, do the same with the bitmaps corresponding to the reference tips that the client advertised as already having. Call this bitmap H.
  • Finally, compute W AND NOT H to produce the set of objects the client needs (in other words, everything it wants but does not already have). Then, send those objects.

Because all of the reachability information is encoded directly into the bitmaps, Git saves time by avoiding the need to open up and parse objects, allowing it to produce the same result in a fraction of the time.

This idea has been used since at least the 1970s to speed up queries in relational databases. In Git, reachability bitmaps can provide dramatic speed-ups when walking objects that reside in the same pack: walking all of the objects in the Linux kernel repository took more than 33 seconds without bitmaps, but only 1.57 seconds to perform the same traversal with bitmaps.

The object order

How does Git turn a set of objects into a sequence of bit positions? One way you might imagine to do this is assign bit positions in lexicographic order. The first bit corresponds to 000023961a, the second to 0000d6543f, the third to 000182eacf, and so on in lexical order.

Why not do this? Recall that an object’s ID is determined by a SHA-1 of its contents, which means that reachability of any object in this order is only reachable to nearby objects by chance. And reachability of nearby objects matters: Git compresses the bitmaps using EWAH compression, which relies on having long runs of identical bits. If the object order makes reachability look essentially random from bit to bit, Git won’t be able to efficiently compress the bitmaps.

Pack order—that is, the physical arrangement of objects in a packfile—produces a sequence of bit positions that tends to place reachable objects next to each other. And this produces exactly the kind of long runs of identical bits that make EWAH compression perform well.

The problem

But, all of this creates a problem for us: if the order of bit positions is dictated by a pack, then bitmaps are coupled in implementation and in concept to the existence of a single packfile. So, any objects that accumulate outside of the bitmapped pack won’t benefit from the same speed-ups.

To address this, we periodically repack the repository’s entire contents into a single pack, and then generate a new reachability bitmap. This makes reachability queries in more recent parts of the repository’s history faster.

But generating that new pack takes time; in fact, it’s quadratic. Bigger repositories take longer to repack, but also grow at a faster rate, which means they run maintenance more often. This compounding effect sometimes makes it such that some repositories are constantly undergoing maintenance: by the time one maintenance job has finished, another is already sitting in the queue, waiting to be run.

Since the bottleneck for maintenance is the compression of an entire repository’s contents into a single packfile, what would it take to be able to repack the contents into multiple packfiles instead?

Multi-pack indexes

To order a set of objects spanning multiple packs, we looked to a recent Git feature: multi-pack indexes.

When Git wants to locate an object by name in a single pack, it uses that pack’s index (.idx) file, which provides a binary-searchable list of object locations. Multi-pack indexes work similarly to .idx files, but the location they indicate is a pair containing both the pack containing the object, as well as where in that pack the object can be found.

The figure above gives a flavor for what kind of data is organized in a multi-pack index. Here, there are three packs, each with a handful of objects. The multi-pack index stores the location of each unique object among the set of packs. When multiple copies of an object exist (like the green or red objects in packs xyz and abc), ties are broken in favor of the copy in the pack with the earliest modification time.

The order of objects in the multi-pack index differs from the order in each individual pack. Since a pack is free to store objects in any order it wants, the multi-pack index stores objects in lexicographic order so that an object can be found quickly by name using a binary search.

Ordering objects

Given a multi-pack index, how should we order the objects in the packs it contains? We discussed earlier that ordering objects lexicographically results in poor compression. We also noted that objects in packs are ordered topologically, which for our purposes we can consider to imply that individual objects tend to appear near other objects which they reach in this order.

So, any ordering of the objects in a multi-pack index should capture as much of those two properties as possible. With that in mind, we decided on the following order:

  • Objects are first grouped according to which packfile they appear in, and packs are ordered according to the multi-pack index.
  • Objects within the same pack should be ordered according to their locations within that pack.

This effectively concatenates the pack-order of multiple packs together, according to some other ordering defined on the packs themselves.

To see what this looks like, let’s overlay a portion of a bitmap that covers the objects in our earlier example:

The first three bits correspond to the red, yellow, and green objects, respectively. Each one of those objects comes from the xyz pack, which means that the xyz pack has the oldest modification among the three. Scanning the bitmap from left to right, these objects appear in pack order; that is, the byte offset of the red object is less than the byte offsets of the yellow and green objects that follow it.

The purple and blue objects come next, since they are in the pack that follows. But note that the copies of the red and green objects in the abc pack don’t correspond to any bits highlighted. Why? Because the multi-pack index selected the copy of those objects in the earlier pack.

Finally, the orange and pink objects appear, also in pack order. And, as we expect, the copy of the purple object that appears in pack 123 isn’t included in the bitmap, because the copy in pack abc was.

This ordering gives us great locality, but we still need to address how to map bit positions back to the objects they represent. For example, let’s look at the fifth bit position, which we know refers to the blue object: how could Git discover this same fact?

You could reasonably imagine that knowing how many total objects are in each pack would be good enough to figure out which objects each bit corresponds to. But that isn’t enough information; we don’t know how many unique objects selected by the multi-pack index appear in each pack, and we also don’t know which non-unique objects are missing. So it’s not good enough to count past the three bits corresponding to objects in pack xyz and then count two more bits up to the fifth bit, because that would point at the copy of the green object in pack abc.

Reverse indexes

To solve this problem, we introduced reverse indexes. In the same way that the pack index provides a mapping from object name to object location, the reverse index maps an object’s location back to its name.

The idea is simple: in addition to the pack’s contents (stored in a .pack file) and index (stored in an .idx file), we’ll write an array of numbers (which comprise the reverse index, and are stored in a new .rev file). These numbers provide a mapping between an object’s position in pack order and its position in lexicographic order.

To better understand this, let’s take a look at an example on a single pack.

The .idx file (shown in the lower left) lists objects in lexicographic order: the yellow object comes before the red one, and the red one comes before the green one. But their pack order is different: there, the red object comes before the yellow one instead of the other way around. The reverse index helps us unwind the two: it tells us that the red object is in the position 3 in lexicographic order, and the yellow object is in position 1.

The reverse index allows us to map quickly from offsets into the packfile to object positions they correspond to. That allows us to quickly determine the size of a packed object. For example, say that you want to figure out how large the red object is. Because Git doesn’t store that information directly, you have one of two options: either scan linearly through the packed data (inflating its contents until you locate the stream end), or locate the adjacent object (in this case, the yellow one) by name, and measure the difference of their offsets.

Without the reverse index, there is no way to figure out where the adjacent object starts. But with a reverse index, locating the red object is as simple as reading the adjacent entry in the reverse index to discover the offset. Here, that value is 1, which points at an entry in the .idx file, which in turn points at the location in the pack.

Before the on-disk reverse index, Git computed this table on the fly and stored the results in an array in memory. This had a couple of major downsides. To build a reverse index on the fly, Git has to allocate a pair of pack offset and index position. This requires memory and runtime, which both scale relative to the size of the pack. Even though this processes using radix sort, sorting the reverse index entries can be noticeably slow when done once per process.

Some initial testing of these reverse indexes showed that they could enable rather dramatic speed-ups when serving fetches on real-world repositories. To verify our early results, we gradually rolled out reverse indexes on a handful of repositories.

Below is the 50th percentile of CPU time for fetches to Homebrew/homebrew-core on our testing host before and after the change:

In this case, we reduced the amount of time it took to serve any fetch of that repository by around 80%. Here’s another plot from the same time which shows the resident set size of the program used to serve fetches by replicas of that same repository:

Encouraged by our first results in production, we proceeded to cautiously roll out on-disk reverse indexes to all other replicas. Once we completed the roll-out, we let a couple of days pass in order for replicas to have enough time to generate reverse indexes. Then, we sampled the overall CPU time it took to serve fetches across all repositories and observed the drop we were hoping for:

In the graph above, you can see three 24-hour cycles. The first day was before we rolled out .rev files, and the second two peaks are after. The per-day peaks dropped from around 10.8 seconds to 7 seconds, for a collective savings of around 35% on all repositories.

Multi-pack bitmaps

Now that we have a format for .rev files, we can reuse it as the missing piece we need to build multi-pack bitmaps. Instead of writing positions relative to a pack .idx file, a multi-pack reverse index writes positions which are relative to a multi-pack-index file.

This provides exactly the information we need to rediscover the mapping between bit positions and the objects they refer to in the multi-pack index. To see why, let’s take a look at another example:

To figure out that the fifth bit corresponds to the blue object in the above diagram, we read the fifth entry in the multi-pack reverse index and get back that the fifth bit maps to the eleventh object in the multi-pack index. And, sure enough, the 11th object points back to the blue object that we were looking for in pack abc.

Putting it all together, this gives us a bitmap which can refer to objects in multiple packs. Based on its filename, each bitmap knows whether or not it belongs to a pack (and if so, which one) or to a multi-pack index. And based on that information, it can translate its object lookups to be relative to a packfile, or to the multi-pack index via its reverse index.

Since we chose the ordering carefully, these multi-pack bitmaps compress exactly as well as their single-pack counterparts. And they decouple bitmaps from individual packs. So, a repository can still have at most one bitmap, but that bitmap can now correspond to multiple packs.

Geometric repacking

Now that we can include multiple packs in a single bitmap, what’s the best way to repack a repository during maintenance?

With single-pack bitmaps, the only option was to pack everything together into one enormous pack. But now that this restriction no longer exists, we have to figure out the best way to repack the objects. When deciding on a new repacking strategy, we wanted something that struck a balance between two properties:

  • On average, there is a relatively small number of packs in the repository.
  • On average, we create a pack that collects objects that were pushed since the last maintenance run.

We decided on an invariant to ensure that the packs in a repository form a geometric progression by object size. In particular, if you sort the packs by number of objects, with the first pack having the most and the final pack having the least, then each pack will contain at least twice as many objects as the next one.

We taught git repack a new --geometric= mode, which creates exactly this geometric progression. Soon (at the time of writing, these patches are still being submitted and reviewed), you’ll be able to try this yourself on your own repository by running:

$ packsizes() {
    find .git/objects/pack -type f -name '*.pack' |
    while read pack; do
      printf "%7d %s\n" \
        "$(git show-index < ${pack%.pack}.idx | wc -l)" "$pack"
    done | sort -rn
  }
$ packsizes # before
$ git repack --write-midx --write-bitmap-index -d --geometric=2
$ packsizes # after

How does this command work? We select a set of packs and combine their objects into one new pack that replaces the set. But picking this set optimally is NP-hard, so we have to approximate it.

To see how we perform that approximation, let's walk through an example. The first step is to figure out how many packs already form a geometric progression. To do this, imagine ordering packs by how many objects they contain. Then, consider each adjacent pair of packs from largest to smallest. At each step, ask: "is the larger pack at least twice the size of the smaller one?". If so, then every pack from that pair onwards already forms a geometric progression.

In this example, the second and third packs (each containing one object) violate our progression. At that point, we know that the second pack, and any packs below it must be repacked together in order to restore the progression.

But we can't just repack the first two packs together, since the combined pack would still be too big (it would contain two objects, and the third pack only contains one). So we grow the set of packs to combine until the invariant is restored:

Here, we had to combine the first four packs together in order to restore a geometric progression. Those packs together contain 7 objects, which is less than half of the next-largest pack (which contains 32 objects). And we can't combine any more packs, since doing so would violate the remainder of the progression.

At this point, we can write a new pack containing just the objects in the set of packs we combined in the previous step. After discarding the now-redundant packs, the remaining packs again form a geometric progression:

This means that the number of packs grow logarithmically over time, so a repository will never have too many packs at any one point in time. It also has the appealing property that older objects tend to get pushed into the larger packs, meaning they get repacked less frequently as time passes. An important corollary of this is that each repack tends to focus on the most recently pushed objects. In other words, this strategy tends to make repacking take time proportional to the number of new objects, not the number of overall objects.

In order to keep the repository performing well over many geometric repacks, we intersperse an all-into-one repack once for every eight geometric repacks.

Importantly, this means that even though the classically-slow repacks are still slow, we aren't forced to run them every time we want to repack a repository.

Deploying to production

Now that we have a way to write a bitmap that covers the objects in multiple packs, a way to quickly map between bit positions and the objects they refer to in a multi-pack index, and a repacking strategy which only requires modifying recent additions to the repository, we are ready to put everything together.

Before rolling out a change as large as this one, we performed extensive local testing to ensure that writing bitmaps worked correctly, and that our new repacking strategy wasn't silently corrupting repositories. But our local testing can only go so far: there are endless corner cases when serving fetches and clones, so the real test occurs only after putting real traffic in front of these new paths. Our goal was to design a deployment strategy that simultaneously exercised enough of those cases, while also ensuring that any potential corruption could never occur on a majority of repository replicas.

Our first test cases were internal repositories. We broke our original tests into two phases. In the first phase, we wrote "multi-pack bitmaps" which contained only a single pack. This allowed us to exercise the most basic case of multi-pack bitmaps (having only one pack) without running our new repack code. Once we had built confidence in that approach, we expanded our test to alternate between geometric and full repacks.

After a couple of weeks without any issues, we were confident enough in our change to start testing it on other repositories external to GitHub. We selected first an individual host, and then a whole rack of hosts on which every repack would alternate between geometric and full. At this stage, results were encouraging: the average time to repack had dropped significantly, as had the overall amount of time spent repacking.

By this stage, our roll-out proceeded for several weeks in only one of three data centers. Because we never place a majority of repository replicas in any single datacenter, this configuration made it impossible for our changes to corrupt a majority set of replicas in an unrecoverable fashion, while still putting our changes in the request path for a large amount of traffic.

Finally, after adopting this configuration for a week, we proceeded to enroll percentages of replicas hosted in other datacenters to also use multi-pack bitmaps until all repositories were using multi-pack reachability bitmaps.

After rolling out our new repacking strategy with multi-pack bitmaps, we saved on average 5.67 CPU days every hour compared to the old strategy.

Likewise, the average time spent repacking any single repository also dropped considerably. Below, the plot is broken out per-site, and you can see when we began testing in a single site, as well as when we expanded our deployment to all sites.

There, the average dropped from around 1 minute to repack a repository to just 15 seconds.

Future directions

There are two major open areas we're considering for the future that will make it possible for further performance improvements:

One open area is the bitmap computation itself. Git's bitmap generation code can reuse existing bitmaps by permuting their bits into a new order, but this operation can still take time proportional to the size of the repository. One way to solve this would be to write bitmaps incrementally, only walking the new objects introduced since the last time a bitmap was written. This problem is tricky because it requires not only that the bitmap file be able to be written incrementally, but also that the object ordering we select is stable: that is, that introducing new bitmaps won't render the existing ones meaningless.

Another open area is the pack structure. Creating packs that form a geometric sequence is a promising step forward that allows us to trade off between full and partial repacks. But some repositories are so large that repacking the whole repository isn't feasible, much less desirable. Designing a strategy which freezes the packs containing the oldest objects in a repository's history will allow us to grow to support even larger repositories in the future.

Thank you

This project would not have been possible without help from the upstream Git community, as well as many engineering teams within GitHub. Each of these changes required extensive review, both to the Git project, as well as to internal GitHub services. Special thanks to Jeff King, Derrick Stolee, Jonathan Tan, Junio Hamano, and others for making this possible.

GitHub Desktop supports hiding whitespace, expanding diffs, and creating repository aliases

Post Syndicated from Billy Griffin original https://github.blog/2021-04-28-github-desktop-hiding-whitespace-expanding-diffs-repo-aliases/

GitHub Desktop 2.8 now includes several new features to make it easier to work with diffs and easier for people who have multiple copies of the same repository.

Expand diffs to get more context around changes

We hear a lot about how people love the way GitHub Desktop displays diffs beautifully, but you’re only able to see a few lines around the changes that you or someone else made. Now you can click to expand the diffs above or below your changes to get a more complete picture of the rest of the file around the changes made. You can also use a context menu on the diff to expand the whole file.

Hide whitespace in diffs

Similar to being able to see more context around your changes, sometimes there are a lot of whitespace changes in a file that don’t allow you to get a clear picture of the substantive changes that happened. Now, in both changes and history, you can optionally hide whitespace changes to allow you to focus just on the more meaningful changes to your code. This feature was built almost entirely by Steven Yeh (@say25), a fantastic and close community contributor to GitHub Desktop. Steven is a long-time open source contributor to GitHub Desktop, and we’re immensely grateful for him continuing to help improve the product.

Create aliases for repositories locally

Many developers keep more than one copy of a repository in GitHub Desktop, and the way repositories are displayed makes it tricky to differentiate between them. In GitHub Desktop 2.8, you can create aliases for your local repositories to easily tell them apart in the list.

We appreciate your input

All of the recent features we’ve shipped have come as a direct result of the great feedback we get from talking with users and hearing from you in our open source repository. With more than one million users actively using GitHub Desktop every month and more than 200 community contributors, we so appreciate all the feedback and contributions that help make GitHub Desktop even better every day. Thank you!

And if you’ve never tried it, or have not tried it in awhile, download GitHub Desktop today.

List of Open Source Security Tools

Post Syndicated from Bozho original https://techblog.bozho.net/list-of-open-source-security-tools/

As a founder of a security company, I’m constantly looking for open source tools to either incorporate in our offering, or get inspiration from, or provide integration with. And there are dozens of great open source security tools, so I decided to publish a list of them. This plethora of options is one of the reasons that security is so hard – they are many different ways to achieve something and it almost always involves headaches with configuring and connecting various “point solutions” (as marketers call them). So here’s the list in on apparent order (note that I’ve listed only defensive tools, offensive ones like metasploit, nmap, wireshark, etc. probably deserve a separate post):

Security monitoring, intrusion detection/prevention

  • Suricata – intrusion detection system
  • Snort – intrusion detection system
  • Zeek – network security monitoring
  • OSSEC – host-based intrusion detection system
  • Wazuh – a more active fork of OSSEC
  • Velociraptor – endpoint visibility and response
  • OSSIM – open source SIEM, at the core of AlienVault
  • SecurityOnion – security monitoring and log management
  • Elastic SIEM – SIEM functionality by Elasticsearch
  • Mozdef – SIEM-like layer ontop of
    Elasticsearch
  • Sagan – log analytics and correlation
  • Apache Metron – (retired) network security monitoring, evolved from Cisco OpenSOC
  • Arkime – packet capture and search tool (formerly Moloch)
  • PRADAS – real-time asset detection
  • BloodHound – ActiveDirectory relationship detection

Threat intelligence

  • MISP – threat intelligence platform
  • SpiderFoot – threat intelligence aggregation
  • OpenCTI – threat intelligence platform
  • OpenDXL – open source tools for security intelligence sharing

Incident response

Vulnerability assessment

  • OpenVAS – very popular vulnerability assessment
  • ZAProxy – web vulnerability scanner by OWASP
  • WebScarab – (obsolete) web vulnerability scanner by OWASP
  • w3af – web vulnerability scanner
  • Loki – IoC scanner
  • CVE Search – set of tools for search in CVE data

Firewall

  • pfsense – the most popular open source firewall
  • OPNSense – hardenedBSD-based firewall
  • Smoothwall – linux-based Firewall

Antivirus / endpoint protection

Email security

I’m sure there are more (and I’d be happy to add them, e.g. this list suggested in reddit, or others in the reddit thread). Assessing each individual tool, its ease of use, its compliance aspects and the combination between multiple tools is a hard task (here’s a SANS paper on “stitching” multiple tools together). And making sense of the whole landscape (as I’ve tried previously) hints about the complexity of a security professional’s job.

The post List of Open Source Security Tools appeared first on Bozho's tech blog.

Stallman isn’t great, but not the devil

Post Syndicated from arp242.net original https://www.arp242.net/rms.html

So Richard Stallman is back at the FSF, on the board of directors this time
rather than as President. I’m not sure how significant this position is in the
day-to-day operations, but I’m not sure if that’s really important.

How anyone could have thought this was a good idea is beyond me. I’ve long
considered Stallman to be a poor representative of the community, and quite
frankly it baffles me that people do. I’m not sure what the politics were that
lead up to this decision; I had hoped that after Stallman’s departure the FSF
would move forward and shed off some of the Stallmanisms. It seems this hasn’t
happened.

To quickly recap why Stallman is a poor representative:

  • Actively turned many people off because he’s such a twat; on of the better
    examples I know of is from Keith Packard, explaining why X didn’t use the
    GPL in spite of Packard already having used it for some of his projects
    before:

    Richard Stallman, the author of the GPL and quite an interesting individual
    lived at 5405 DEC square, he lived up on the sixth floor I think? Had an
    office up there; he did not have an apartment. And we knew him extremely
    well. He was a challenging individual to get along with. He would regularly
    come down to our offices and ask us, or kind of rail at us, for not using
    the GPL.

    This did not make a positive impression on me; this was my first
    interactions with Richard directly and I remember thinking at the time,
    “this guy is a little, you know, I’m not interesting in talking to him
    because he’s so challenging to work with.”

    And so, we should have listened to him then but we did not because, we know
    him too well, I guess, and met him as well.

    He really was right, we need to remember that!

  • His behaviour against women in particular is creepy. This is not a crime (he
    has, as far as I know, never forced himself on anyone) but not a good quality
    in a community spokesperson, to put it mildly.

  • His personal behaviour in general is … odd, to put it mildly. Now, you can
    be as odd as you’d like as far as I’m concerned, but I also don’t think
    someone like that is a good choice to represent an entire community.

  • Caused a major and entirely avoidable fracture of the community with the Open
    Source
    movement; it’s pretty clear that Stallman, him specifically as a
    person, was a major reason for the OSI people to start their own organisation.
    Stallman still seems to harbour sour grapes over this more than 20 years
    later.

  • Sidetracking of pointless issues (“GNU/Linux”, “you should not be using hacker
    but cracker”, “Open Source misses the point”, etc.), as well as stubbornly
    insisting on the term “Free Software” which is confusing and stands in the way
    if communicating the ideals to the wider world. Everyone will think that an
    article with “Free Software” in the title will be about software free of
    charge. There is a general lack of priorities or pragmatism in almost
    anything Stallman does.

  • Stallman’s views in general on computing are stuck somewhere about 1990.
    Possibly earlier. The “GNU Operating System” (which does not exist, has never
    existed, and most likely will never exist[1]) is not how to advance Free
    Software in modern times. Most people don’t give a rat’s arse which OS they’re
    using to access GitHub, Gmail, Slack, Spotify, Netflix, AirBnB, etc. The world
    has changed and the strategy needs to change – but Stallman is still stuck in
    1990.

  • Insisting on absolute freedom to the detriment of more freedom compared to
    the status quo. No, people don’t want to run a “completely free GNU/Linux
    operating system” if their Bluetooth and webcam doesn’t work and if they can’t
    watch Netflix. That’s just how it is. Deal with it.

    His views are quite frankly ridiculous:

    If [an install fest] upholds the ideals of freedom, by installing only free
    software from 100%-free distros, partly-secret machines won’t become
    entirely functional and the users that bring them will go away disappointed.
    However, if the install fest installs nonfree distros and nonfree software
    which make machines entirely function, it will fail to teach users to say no
    for freedom’s sake. They may learn to like GNU/Linux, but they won’t learn
    what the free software movement stands for.

    [..]

    My new idea is that the install fest could allow the devil to hang around,
    off in a corner of the hall, or the next room. (Actually, a human being
    wearing sign saying “The Devil,” and maybe a toy mask or horns.) The devil
    would offer to install nonfree drivers in the user’s machine to make more
    parts of the computer function, explaining to the user that the cost of this
    is using a nonfree (unjust) program.

    Aside from the huge cringe factor of having someone dressed up as a devil to
    install a driver, the entire premise is profoundly wrong; people can
    appreciate freedom while also not having absolute/maximum freedom. Almost the
    entire community does this, with only a handful of purist exceptions. This
    will accomplish nothing except turn people off.

  • Crippling software out of paranoia; for example Stallman refused to make gcc
    print the AST
    – useful for the Emacs completion and other tooling –
    because he was afraid someone might “abuse” it. He comes off as a gigantic
    twat in that entire thread (e.g. this).

    How do you get people to use Free Software? By making great software people
    want to use
    . Not by offering some shitty crippled product where you can’t do
    some common things you can already do in the propetariy alternatives.


Luckily, the backlash against this has been significant, including an An open
letter to remove Richard M. Stallman from all leadership positions
. Good.
There are many things in the letter I can agree with. If there are parliamentary
hearings surrounding some Free Software law then you would you want Stallman to
represent you? Would you want Stallman to be left alone in a room with some
female lawmaker (especially an attractive one)? I sure wouldn’t; I’d be fearful
he’d leave a poor impression, or outright disgrace the entire community.

But there are also a few things that bother me, as are there in the general
conversation surrounding this topic. Quoting a few things from that letter:

[Stallman] has been a dangerous force in the free software community for a
long time. He has shown himself to be misogynist, ableist, and transphobic,
among other serious accusations of impropriety.

[..]

him and his hurtful and dangerous ideology

[..]

RMS and his brand of intolerance

Yikes! That sounds horrible. But closer examinations of the claims don’t really
bear out these strong claims.

The transphobic claim seems to hinge entirely on his eclectic opinion regarding
gender-neutral pronouns; he prefers some peculiar set of neologisms (“per”
and “pers”) instead of the singular “they”. You can think about his pronoun
suggestion what you will – I feel it’s rather silly and pointless at best – but
a disagreement on how to best change the common use of language to be more
inclusive does not strike me as transphobic. Indeed, it strikes me as the exact
opposite
: he’s willing to spend time and effort to make language more
inclusive
. That he doesn’t do it in the generally accepted way is not
transphobia, a “harmful ideology”, or “dangerous”. It’s really not.

Stallman is well known for his excessive pedantry surrounding language;
he’s not singularly focused on the issue of pronouns and has consistently
posted in favour of trans rights
.

Stallman’s penchant to make people feel unconformable has long been known; and
should hardly come as a surprise to anyone. Many who met him in person did not
leave with an especially good impression of him for one reason or the other. His
behaviour towards women in particular is pretty bad; many anecdotes have been
published and they’re pretty 😬

But … I don’t have the impression that Stallman dislikes or distrusts women,
or sees them as subservient to men. Basically, he’s just creepy. That’s not
good, but is it misogyny? His lack of social skills seem to be broad and not
uniquely directed towards women. He’s just a socially awkward guy in general. I
mean, this is a guy who will, when giving a presentation, will take off his
shoes and socks – which is already a rather weird thing to do – will then
proceed to rub his bare foot – even weirder – only to proceed to appear to
eat something from his foot – wtf wtf wtf?!

If he can’t understand that this is just … wtf, then how can you expect him to
understand that some comment towards a woman is wtf?

Does all of this excuse bad behaviour? No. But it shines a rather different
light on things than phrases such as “misogynist”, “hurtful and dangerous
ideology”, and “his brand of intolerance” do. He hasn’t forced himself on
anyone, as far as I know, and most complaints are about him being creepy.

I don’t think it’s especially controversial to claim that Stallman would have
been diagnosed with some form of autism if he had been born several decades
later. This is not intended as an insult or some such, just to establish him as
a neurodivergent[2] individual. Someone like that is absolutely a poor choice
for a leadership position, but at the same time doesn’t diversity also mean
diversity of neurodivergent people, or at the very least some empathy and
understanding when people’s exhibit a lack of social skills and behaviour
considered creepy?

At what point is there a limit if someone’s neurodiversity drives people away? I
don’t know; there isn’t an easy answer to his. Stallman is clearly unsuitable
for a leadership role; but “misogynist”? I’m not really seeing it in Stallman.

The ableist claim seems to mostly boil down to a comment he posted on his
website regarding abortion of fetuses with Down’s syndrome:

A new noninvasive test for Down’s syndrome will eliminate the small risk of
the current test.

This mind lead more women to get tested, and abort fetuses that have Down’s
syndrome. Let’s hope so!

If you’d like to love and care for a pet that doesn’t have normal human mental
capacity, don’t create a handicapped human being to be your pet. Get a dog or
a parrot. It will appreciate your love, and it will never feel bad for being
less capable than normal humans.

It was later edited to its current version:

A noninvasive test for Down’s syndrome eliminates the small risk of the old
test. This might lead more women to get tested, and abort fetuses that have
Down’s syndrome.

According to Wikipedia, Down’s syndrome is a combination of many kinds of
medical misfortune. Thus, when carrying a fetus that is likely to have Down’s
syndrome, I think the right course of action for the woman is to terminate the
pregnancy.

That choice does right by the potential children that would otherwise likely
be born with grave medical problems and disabilities. As humans, they are
entitled to the capacity that is normal for human beings. I don’t advocate
making rules about the matter, but I think that doing right by your children
includes not intentionally starting them out with less than that.

When children with Down’s syndrome are born, that’s a different situation.
They are human beings and I think they deserve the best possible care.

He also made a few other comments to the effect of “you should abort if you’re
pregnant with a fetus who has Down’s syndrome”.

That last paragraph of the original version was … not great, but the new
version seems okay to me. It is a women’s right to choose to have an abortion,
for any reason, including not wanting to raise a child with Down’s syndrome.
This is already commonplace in practice, with many women choosing to do so.

Labelling an entire person as ableist based only on this – and this is really
the only citation of ableism I’ve been able to find – seems like a stretch, at
best. It was a shitty comment, but he did correct it which is saying a lot in
Stallman ters, as I haven’t seen him do that very often.


Phrases like “a dangerous force”, “dangerous ideology”, and “brand of
intolerance” make it sound like he’s crusading on these kind of issues. Most of
these are just short notes on his personal site which few people seem to read.

Most of the issues surrounding Stallman seem to be about him thinking out loud,
not realizing when it is or is not appropriate to do so, being excessively
pedantic over minor details, or just severally lacking in social skills. This can
be inappropriate, offensive, or creepy – depending on the scenario – but that’s
just something different than being actively transphobic or dangerous. If
someone had read only this letter without any prior knowledge of Stallman they
would be left with the impression that Stallman is some sort of alt-right troll
writing for Breitbart or the like. This is hardly the case.

I think Stallman should resign of newly appointed post, and from GNU as well,
over his personal behaviour in particular. Stallman isn’t some random programmer
working on GNU jizamabob making the occasional awkward comment, he’s the face of
the entire movement. Appointing “a challenging individual to get along with” –
to quote Packard – is not the right person for the job. I feel the rest of the
FSF board has shown spectacular poor judgement in allowing Stallman to come
back.[3]

But I can not, in good conscience, sign the letter as phrased currently. It
vastly exaggerates things to such a degree that I feel it does a gross injustice
to Stallman. It’s grasping at straws to portray Stallman as the most horrible
human being possible, and I don’t think he is that. He seems clueless on some
topics and social interactions, and find him a bit of a twat in general, but
that doesn’t make you a horrible and dangerous person. I find the letter lacking
in empathy and deeply unkind.


In short, I feel Stallman’s aptitudes do not apply well for any sort of
leadership position and I would rather not have him represent the community I’m
a part of, even if he did start it and made many valuable contributions to it.
Just starting something does not give you perpetual ownership over it, and in
spite of all his hard work I feel he’s been very detrimental to the movement and
has been a net-negative contributor for a while. A wiser version of Stallman
would have realized his shortcomings and stepped down some time in the late 80s
to let someone else be the public face.
Overall I feel he’s not exactly a shining example of the human species, but then
again I’m probably not either. He is not the devil and the horrible person that
the letter makes him out to be. None of these exaggerations are even needed to
make the case that he should be removed, which makes it even worse.

It’s a shame, because instead of moving forward with Free Software we’re
debating this. Arguably I should just let this go as Stallman isn’t really
worth defending IMO, but on the other hand being unfair is being unfair, no
matter who the target may be.

Footnotes

  1. A set of commandline utilities, libc, and a compiler are not an
    operating system. Linux (the kernel) is not the “last missing piece of
    the GNU operating system”. 

  2. Neurodivergency is, in a nutshell, the idea that “normal” is a wide
    range, and that not everyone who doesn’t fits with the majority should be
    labelled as “there is something wrong with them” such as autism. While
    some some people take this a bit too far (not every autist is
    high-functioning; for some it really is debilitating) I think there’s
    something to this. 

  3. I guess this shouldn’t come as that much of a surprise, as the only people
    willing and able to hang around Stallman’s FSF were probably similar-ish
    people. It’s probably time to just give up on the FSF and move forward
    with some new initiative (OSI is crap too, for different reasons). I swear
    we’ve got to be the most dysfunctional community ever. 

Packaging award-winning shows with award-winning technology

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/packaging-award-winning-shows-with-award-winning-technology-c1010594ba39

By Cyril Concolato

Introduction

In previous blog posts, our colleagues at Netflix have explained how 4K video streams are optimized, how even legacy video streams are improved and more recently how new audio codecs can provide better aural experiences to our members. In all these cases, prior to being delivered through our content delivery network Open Connect, our award-winning TV shows, movies and documentaries like The Crown need to be packaged to enable crucial features for our members. In this post, we explain these features and how we rely on award-winning standard formats and open source software to enable them.

The Crown

Key Packaging Features

In typical streaming pipelines, packaging is the step that happens just after encoding, as depicted in the figure below. The output of an encoder is a sequence of bytes, called an elementary stream, which can only be parsed with some understanding of the elementary stream syntax. For example, detecting frame boundaries in an AV1 video stream requires being able to parse so-called Open Bitstream Units (OBU) and identifying Temporal Delimiters OBU. However, high level operations performed on client devices, such as seeking, do not need to be aware of the elementary syntax and benefit from a codec-agnostic format. The packaging step aims at producing such a codec-agnostic sequence of bytes, called packaged format, or container format, which can be manipulated, to some extent, without a deep knowledge of the coding format.

Figure 1 — Simplified architecture of a streaming preparation pipeline

A key feature that our members rightfully deserve when playing audio, video, and timed text is synchronization. At Netflix, we strive to provide an experience where you never see the lips of the Queen of England move before you hear her corresponding dialog in The Crown. Synchronization is achieved by fundamental elements of signaling such as clocks or time lines, time stamps, and time scales that are provided in packaged content.

Our members don’t simply watch our series from beginning to end. They seek into Bridgerton when they resume watching. They rewind and replay their favorite chess move in The Queen’s Gambit. They skip introductions and recaps when they frantically binge-watch Lupin. They make playback decisions when they watch interactive titles such as You vs. Wild. Due to the nature of the audio or video compression techniques, a player cannot necessarily start decoding the stream exactly where our members want. Under the hood, players have to locate points in the stream where decoding can start, decode as quickly as they can, until the user seek point is reached before starting playback. This is another basic feature of packaging: signaling frame types and particularly Random Access Points.

When our members’ kids watch Carmen Sandiego in the back seats of their parents’ car or more generally when the network throughput varies, adaptive streaming technologies are applied to provide the best viewing experience under the network conditions. Adaptive streaming technologies require that streams of various qualities be encoded to common constraints but they also rely on another key feature of packaging to offer seamless quality switching, called indexing. Indexing lets the player fetch only the corresponding segments of the new stream.

Many other elements of signaling are provided in our packaged content to enable the viewing to start as quickly as possible and in the best possible conditions. Decryption modules need to be initialized with the appropriate scheme and initialization vector. Hardware video decoders need to know in advance the resolution and bit depth of the video streams to allocate their decoding buffers. Rendering pipelines need to know ahead of time the speaker configuration of audio streams or whether the video streams are HDR or SDR. Being able to signal all these elements is also a key feature of modern packaging formats.

The role of standards and open source software

Our 200+ million members watch Netflix on a wide variety of devices, from smartphones, to laptops, to TVs and many more, developed by a large number of partners. Reducing the friction when on-boarding a new device and making sure that our content will be playable on old devices for a long time is very important. That is where standards play a key role. The ISO Base Media File Format (ISOBMFF) is the key packaging standard in the entertainment industry as recently recognized with a Technology & Engineering Emmy® Award by the National Academy of Television Arts & Sciences (NATAS).

ISOBMFF provides all the key packaging features mentioned above, and as history proves, it is also versatile and extensible, in its capabilities of adding new signaling features and in its support of codec. Streams encoded with well-established codecs such as AVC and AAC can be carried in ISOBMFF files, but the specification is also regularly extended to support the latest codecs. The Media Systems team at Netflix actively contributes to the development, the maintenance, and the adoption of ISOBMFF. As an example, Netflix led the specification for the carriage of AOM’s AV1 video streams in ISOBMFF.

With 20+ years of existence, ISOBMFF accumulated a lot of technical tools for various use cases. Figure 2 illustrates the complexity of ISOBMFF today through the concept of ‘brands’, a concept similar to profiles in audio or video standards. Initially, limited and well-nested, the standard is now very broad and evolving in various directions.

Figure 2 — Illustrating the complexity of the 6th edition of ISOBMFF. Each rectangle represents a ‘brand’ (indicated by a four character code in bold), and its required set of tools (indicated by a ‘+’ line). Brands are nested. All the tools of inner brands are required by outer brands.

For the Netflix streaming service, we rely on a subset of these tools as identified by the Common Media Application Format (CMAF) standard, and the content protection tools defined in the Common Encryption (CENC) standard.

Multimedia standards like ISOBMFF, CMAF and CENC go hand in hand with open source software implementations. Open source software can demonstrate the features of the standard, enabling the industry to understand its benefits and broadening its adoption. Open source software can also help improve the quality of a standard by highlighting possible ambiguities through a neutral, reference implementation. The Media Systems team at Netflix maintains such a reference open source implementation, called Photon, for the SMPTE IMF standard. For ISOBMFF, Netflix uses MP4Box, the reference open source implementation from the GPAC team.

In this packaging ecosystem of standards and open source software, our work within the Media Systems team includes identifying the tools within the existing standards to address new streaming use cases. When such tools don’t exist, we define new standards or expand existing ones, including ISOBMFF and CMAF, and support open source software to match these standards. For example, when our video encoding colleagues design dynamically optimized encoding schemes producing streaming segments with variable durations, we modify our workflow to ensure that segments across video streams with different bit rates remain time aligned. Similarly, when our audio encoding colleagues introduce xHE-AAC, which obsoletes the old assumption that every audio frame is decodable, we guarantee that audio/video segments remain aligned too. Finally, when we want to help the industry converge to a common encryption scheme for new video codecs such as AV1, we coordinate the discussions to select the scheme, in this case pattern-based subsample encryption (a.k.a ‘cbcs’), and lead the way by providing reference bitstreams. And of course, our work includes handling the many types of devices in the field that don’t have proper support of the standards.

Conclusion

We hope that this post gave you a better understanding of a part of the work of the Media Systems team at Netflix, and hopefully next time you watch one of our award-winning shows, you will recognize the part played by ISOBMFF, a key, award-winning technology. If you want to explore another facet of the team’s work, have a look at the other award-winning technology, TTML, that we use for our Japanese subtitles.

We’re hiring!

If this work sounds exciting to you and you’d like to help the Media Systems team deliver an even better experience, Netflix is searching for an experienced Engineering Manager for the team. Please contact Anne Aaron for more info.


Packaging award-winning shows with award-winning technology was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

CDK Corner – January 2021

Post Syndicated from Christian Weber original https://aws.amazon.com/blogs/devops/cdk-corner-february-2021/

Social: Events in the Community

CDK Day is coming up on April 30th! This is your chance to meet and engage with the CDK Community! Last year’s event included an incredible amount of content, whether it was learning the origin story of CDK, learning how CDK is used in a Large Enterprise, there were many great sessions, as well as Eric Johnson cosplaying as the official CDK Mascot.

Do you have a story to share about using CDK, about something funny/crazy/interesting/cool/another adjective? The CFPs are now open — the community wants to hear your stories; so go ahead and submit here!

Updates: Changes made across CDK

In January, the CDK Community and the AWS CDK team were together hard at work, bringing in new changes, features, or, as NetaNir likes to call them, many new “goodies” to the CDK!

AWS Construct Library and Core

The CDK Team announced General Availability of the EKS Module in CDK with PR#12640. Moving a CDK Module from Experimental to Stable requires substantial effort from both the CDK Community and Team — the appreciation for everyone that contributed to this effort cannot be understated. Take a look at the project milestone to explore some of the work that contributed to releasing the EKS constrcut to GA. Great job everyone!

External assets are now supported from PR#12259. With this change, you can now setup cdk-assets.json with Files, Archives, or even Docker Images built by external utilities. This is great if your CDK Application relies on assets from other sources, such as an internal pipeline, or if you want to pull the latest Docker Image built from some external utility.

CDK will now alert you if your stack hits the maximum number of CloudFormation Resources. If you’re deploying complex CDK Stacks, you’ll know that sometimes you will hit this cap which seems to only happen when you’ve walked away from your computer to make a coffee while your stack is deploying, only to come back with a latte and a command line full of exceptions. This wonderful quality-of-life change was merged in PR#12193.

AWS CodeBuild

AWS CodeBuild in CDK can now be configured with Standard 5.0 Runtime Environments, which now supports many new runtime environments, including support for Python 3.9 which means, for example, CodeBuild now natively understands the union operator in Python dictionaries you’ve been using to combine dictionaries in your project.

AWS EC2

There is now support for m6gd and r6gd Graviton EC2 Instances from CDK with PR#12302. Graviton Instances are a great way to utilize ARM Archicture at a lower cost.

Support for new io2 and and gp3 EBS Volumes were announced at re:Invent, followed up with a community contribution from leandrodamascena in PR#12074

AWS ElasticSearch

A big cost savings feature to support ElasticSearch UltraWarm nodes in CDK, now gives CDK users the opportunity to store data in S3 instead of an SSD with ElasticSearch, which can substantially reduce storage costs.

AWS S3

Securing S3 Buckets is a standard practice, and CDK has tightened its security on S3 Buckets by limiting the PutObject permission of Bucket.grantWrite() to just s3:PutObject instead of s3:PutObject*. This subtle change means that only the first permission is added to the IAM Principal, instead of any other IAM permission prefixed with PutObject (Such as s3:PutObjectAcl). You still have the flexibility to make this permission add-on if needed, though.

AWS StepFunctions

A member of the CDK Community, ayush987goyal, submitted PR#12436 for StepFunctions-Tasks. This feature now lets users specify the family and revision of a taskDefinitionFamily inside EcsRunTask, thanks to their effort. This modifies previous behavior of the construct where a user could only deploy the latest revision of a Task by supplying the ARN of the Task.

CloudFormation and new L1 Resources

As CDK synthesizes CloudFormation Templates, it’s important that CDK stays up to date with the CloudFormation Resource Specification these updates to our collection of L1 Constructs. Now that they’re here, the community and team can begin implementing beautiful L2 Constructs for these L1s. Interested in contributing an L2 from these L1s? Take a look at our CONTRIBUTING doc to get up and running.

In January the team introduced several updates of the CloudFormation Resource Spec to CDK, bringing support for a whole slew of new Resources, Attribute Updates and Property Changes. These updates, among others, include new resource types for CloudFormation Modules, SageMaker Pipelines, AWS Config Saved Queries, AWS DataSync, AWS Service Catalog App Registry, AWS QuickSight, Virtual Clusters for EMR Containers for Amazon Elastic MapReduce, support for DNSSEC in Route53, and support for ECR Public Repositories.

My favorite of all these is ECR Public Repositories. Public Repositories support was just recently announced, in December at AWS re:Invent. Now you can deploy and manage a public repository with CDK as an L1 Construct. So, if you have an exciting Container Image that you’ve been wanting to share with the world with your own Public Repository, set it all up with CDK!

To be in the know on updates to the CDK, and updates to CDK’s CloudFormation Resource Spec, update your repository notification settings to watch for new CDK Releases , and browse the cfnspec CHANGELOG.

Learning: Level up your CDK Knowledge

AWS has released a new training module for the CDK. This free 7 module course teaches users the fundamental concepts of the CDK, from explaining its core benefits, to defining the common language and terms, to tips for troubleshooting CDK Projects. This is a great course for developers, or related stakeholders who may be considering whether or not to adopt CDK in their team or organization.

Community Acknowledgements: Thanks for your hard work

We love highlighting Pull Requests from our community of CDK users. This month’s spotlight goes to Jacob-Doetsch, who submitted a fix when deploying Bastion Hosts backed by ARM Architecture. As ARM based architecture increases in usage across AWS, identifying and resolving these types of bugs helps CDK maintain the ability to help Developers continue moving quickly. Great job Jacob!

And finally, to round out the CDK Corner, a round of applause to the following users who merged their first Pull Request to CDK in January! The CDK Community appreciates your hard work and effort!

Announcing Amazon Managed Service for Grafana (in Preview)

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/announcing-amazon-managed-grafana-service-in-preview/

Today, in partnership with Grafana Labs, we are excited to announce in preview, Amazon Managed Service for Grafana (AMG), a fully managed service that makes it easy to create on-demand, scalable, and secure Grafana workspaces to visualize and analyze your data from multiple sources.

Grafana is one of the most popular open source technologies used to create observability dashboards for your applications. It has a pluggable data source model and support for different kinds of time series databases and cloud monitoring vendors. Grafana centralizes your application data from multiple open-source, cloud, and third-party data sources.

Many of our customers love Grafana, but don’t want the burden of self-hosting and managing it. AMG manages the provisioning, setup, scaling, version upgrades and security patching of Grafana, eliminating the need for customers to do it themselves. AMG automatically scales to support thousands of users with high availability.

With AMG, you will get a fully managed and secure data visualization service where you can query, correlate, and visualize operational metrics, logs and traces across multiple data sources including cloud services such as AWS, Google, and Microsoft. AMG is integrated with AWS data sources, such as Amazon CloudWatch, Amazon Elasticsearch Service, AWS X-Ray, AWS IoT SiteWise, Amazon Timestream, and others to collect operational data in a simple way. Additionally, AMG also provides plug-ins to connect to popular third-party data sources, such as Datadog, Splunk, ServiceNow, and New Relic by upgrading to Grafana Enterprise directly from the AWS Console.

Screenshot for creating and configuring a managed Grafana workspace

AMG integrates directly into your AWS Organizations. You can define a AMG workspace in one AWS account that allows you to discover and access datasources in all your accounts and regions across your AWS organization. Creating dashboards in Grafana is easy as all these different datasources are discoverable in one place.

Customers really like Grafana for the ease of creating dashboards, it comes with many built-in dashboards to use when you add a new data source, or you can take advantage of its broad community of pre-built dashboards. For example, you can see in the following image a really nice dashboard that AMG created for me from one of my AWS Lambda function.

Screenshot of an automatic dashboard for Lambda function

One of my favorite things from AMG is the built-in security features. You can easily enable single sign-on using AWS Single Sign-On, restrict access to data sources and dashboards to the right users, and access audit logs via AWS CloudTrail for your hosted Grafana workspace. With AWS Single Sign-On you can leverage your existing corporate directories to enforce authentication and authorization permissions.

Another powerful feature that AMG has is support for Alerts. AMG integrates with Amazon Simple Notification Service (SNS) so customers can send Grafana alerts to SNS as a notification destination. It also has support for four other alert destinations including PagerDuty, Slack, VictorOps and OpsGenie.

There are no up-front investments required to use AMG, and you only pay a monthly active user license fee. This means that you can provision many users to access to your Grafana workspace, but will only be billed for active users that log in and use the workspace that month. Users granted access but that do not log in, will not be billed that month. You can also upgrade to Grafana Enterprise using AWS Marketplace, to get access to enterprise plugins, support, and training content directly from Grafana Labs.

Availability

This service is available in US East (N. Virginia) and Europe (Ireland) regions. To learn more visit the AMG service page, and be sure to join our re:Invent session tomorrow 12/16 from 8:00am – 8:30am PST for a demo!

AMG is now available in preview; to get access to this service fill out the registration form here.

Marcia

New – Managed Data Parallelism in Amazon SageMaker Simplifies Training on Large Datasets

Post Syndicated from Julien Simon original https://aws.amazon.com/blogs/aws/managed-data-parallelism-in-amazon-sagemaker-simplifies-training-on-large-datasets/

Today, I’m particularly happy to announce that Amazon SageMaker now supports a new data parallelism library that makes it easier to train models on datasets that may be as large as hundreds or thousands of gigabytes.

As data sets and models grow larger and more sophisticated, machine learning (ML) practitioners working on large distributed training jobs have to face increasingly long training times, even when using powerful instances such as the Amazon Elastic Compute Cloud (EC2) p3 and p4 instances. For example, using a ml.p3dn.24xlarge instance equipped with 8 NVIDIA V100 GPUs, it takes over 6 hours to train advanced object detection models such as Mask RCNN and Faster RCNN on the publicly available COCO dataset. Likewise, training BERT, a state of the art natural language processing model, takes over 100 hours on the same instance. Some of our customers, such as autonomous vehicle companies, routinely deal with even larger training jobs that run for days on large GPU clusters.

As you can imagine, these long training times are a severe bottleneck for ML projects, hurting productivity and slowing down innovation. Customers asked us for help, and we got to work.

Introducing Data Parallelism in Amazon SageMaker
Amazon SageMaker now helps ML teams reduce distributed training time and cost, thanks to the SageMaker Data Parallelism (SDP) library. Available for TensorFlow and PyTorch, SDP implements a more efficient distribution of computation, optimizes network communication, and fully utilizes our fastest p3 and p4 GPU instances.

Up to 90% of GPU resources can now be used for training, not for data transfer. Distributed training jobs can achieve up near-liner scaling efficiency, regardless of the number of GPUs involved. In other words, if a training job runs for 8 hours on a single instance, it will only take approximately 1 hour on 8 instances, with minimal cost increase. SageMaker effectively eliminates any trade-off between training cost and training time, allowing ML teams to get results sooner, iterate faster, and accelerate innovation.

During his keynote at AWS re:Invent 2020, Swami Sivasubramanian demonstrated the fastest training times to date for T5-3B and Mask-RCNN.

  • The T5-3B model has 3 billion parameters, achieves state-of-the-art accuracy on natural language processing benchmarks, and usually takes weeks of effort to train and tune for performance. We trained this model in 6 days on 256 ml.p4d.24xlarge instances.
  • Mask-RCNN continues to be a popular instance segmentation model used by our customers. Last year at re:Invent, we trained Mask-RCNN in 26 minutes on PyTorch, and in 27 minutes on TensorFlow. This year, we recorded the fastest training time to date for Mask-RCNN at 6:12 minutes on TensorFlow, and 6:45 minutes on PyTorch.

Before we explain how Amazon SageMaker is able to achieve such speedups, let’s first explain how data parallelism works, and why it’s hard to scale.

A Primer on Data Parallelism
If you’re training a model on a single GPU, its full internal state is available locally: model parameters, optimizer parameters, gradients (parameter updates computed by backpropagation), and so on. However, things are different when you distribute a training job to a cluster of GPUs.

Using a technique named “data parallelism,” the training set is split in mini-batches that are evenly distributed across GPUs. Thus, each GPU only trains the model on a fraction of the total data set. Obviously, this means that the model state will be slightly different on each GPU, as they will process different batches. In order to ensure training convergence, the model state needs to be regularly updated on all nodes. This can be done synchronously or asynchronously:

  • Synchronous training: all GPUs report their gradient updates either to all other GPUs (many-to-many communication), or to a central parameter server that redistributes them (many-to-one, followed by one-to-many). As all updates are applied simultaneously, the model state is in sync on all GPUs, and the next mini-batch can be processed.
  • Asynchronous training: gradient updates are sent to all other nodes, or to a central server. However, they are applied immediately, meaning that model state will differ from one GPU to the next.

Unfortunately, these techniques don’t scale very well. As the number of GPUs increases, a parameter server will inevitably become a bottleneck. Even without a parameter server, network congestion soon becomes a problem, as n GPUs need to exchange n*(n-1) messages after each iteration, for a total amount of n*(n-1)*model size bytes. For example, ResNet-50 is a popular model used in computer vision applications. With its 26 million parameters, each 32-bit gradient update takes about 100 megabytes. With 8 GPUs, each iteration requires sending and receiving 56 updates, for a total of 5.6 gigabytes. Even with a fast network, this will cause some overhead, and slow down training.

A significant step forward was taken in 2017 thanks to the Horovod project. Horovod implemented an optimized communication algorithm for distributed training named “ring-allreduce,” which was soon integrated with popular deep learning libraries.

In a nutshell, ring-allreduce is a decentralized asynchronous algorithm. There is no parameter server: nodes are organized in a directed cycle graph (to put it simply, a one-way ring). For each iteration, a node receives a gradient update from its predecessor. Once a node has processed its own batch, it applies both updates (its own and the one it received), and sends the results to its neighbor. With n GPUs, each GPU processes 2*(n-1) messages before all GPUs have been updated. Accordingly, the total amount of data exchanged per GPU is 2*(n-1)*model size, which is much better than n*(n-1)*model size.

Still, as datasets keep growing, the network bottleneck issue often rises again. Enter SageMaker and its new AllReduce algorithm.

A New Data Parallelism Algorithm in Amazon SageMaker
With the AllReduce algorithm, GPUs don’t talk to one another any more. Each GPU stores its gradient updates in GPU memory. When a certain threshold is exceeded, these updates are sharded, and sent to parameter servers running on the CPUs of the GPU instances. This removes the need for dedicated parameter servers.

Each CPU is responsible for a subset of the model parameters, and it receives updates coming from all GPUs. For example, with 3 training instances equipped with a single GPU, each GPU in the training cluster would send a third of its gradient updates to each one of the three CPUs.

Illustration

Then, each CPU would apply all the gradient updates that it received, and it would distributes the consolidated result back to all GPUs.

Illustration

Now that we understand how this algorithm works, let’s see how you can use it with your own code, without having to manage any infrastructure.

Training with Data Parallelism in Amazon SageMaker
The SageMaker Data Parallelism API is designed for ease of use, and should provide seamless integration with existing distributed training toolkits. In most cases, all you have to change in your training code is the import statement for Horovod (TensorFlow), or for Distributed Data Parallel (PyTorch).

For PyTorch, this would look like this.

import smdistributed.dataparallel.torch.parallel.distributed as dist
dist.init_process_group()

Then, I need to pin each GPU to a single SDP process.

torch.cuda.set_device(dist.get_local_rank())

Then, I define my model as usual, for example:

class Net(nn.Module):
    def __init__(self):
        super(Net, self).__init__()
        self.conv1 = nn.Conv2d(1, 32, 3, 1)
        self.conv2 = nn.Conv2d(32, 64, 3, 1)
        self.dropout1 = nn.Dropout2d(0.25)
        self.dropout2 = nn.Dropout2d(0.5)
        self.fc1 = nn.Linear(9216, 128)
        self.fc2 = nn.Linear(128, 10)
...

Finally, I instantiate my model, and use it to create a DistributedDataParallel object like so:

import torch
from smdistributed.dataparallel.torch.parallel.distributed import DistributedDataParallel as DDP
device = torch.device("cuda")
model = DDP(Net().to(device))

The rest of the code is vanilla PyTorch, and I can train it using the PyTorch estimator available in the SageMaker SDK. Here, I’m using an ml.p3.16xlarge instance with 8 NVIDIA V100 GPUs.

from sagemaker.pytorch import PyTorch
estimator = PyTorch(
    entry_point='train_pytorch.py',
    role=sagemaker.get_execution_role(),
    framework_version='1.6.0',
    instance_count=1,
    instance_type='ml.p3.16xlarge',
    distribution={'smdistributed':{'dataparallel':{enabled': True}}}
)
estimator.fit()

From then on, SageMaker takes over and provisions all required infrastructure. You can focus on other tasks while your training job runs.

Getting Started
If your training jobs last for hours or days on multiple GPUs, we believe that the SageMaker Data Parallelism library can save you time and money, and help you experiment and innovate quicker. It’s available today at in all regions where SageMaker is available, at no additional cost.

Examples are available to get you started quickly. Give them a try, and let us know what you think. We’re always looking forward to your feedback, either through your usual AWS support contacts, or on the AWS Forum for SageMaker.

– Julien

Open Source Does Not Equal Secure

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2020/12/open-source-does-not-equal-secure.html

Way back in 1999, I wrote about open-source software:

First, simply publishing the code does not automatically mean that people will examine it for security flaws. Security researchers are fickle and busy people. They do not have the time to examine every piece of source code that is published. So while opening up source code is a good thing, it is not a guarantee of security. I could name a dozen open source security libraries that no one has ever heard of, and no one has ever evaluated. On the other hand, the security code in Linux has been looked at by a lot of very good security engineers.

We have some new research from GitHub that bears this out. On average, vulnerabilities in their libraries go four years before being detected. From a ZDNet article:

GitHub launched a deep-dive into the state of open source security, comparing information gathered from the organization’s dependency security features and the six package ecosystems supported on the platform across October 1, 2019, to September 30, 2020, and October 1, 2018, to September 30, 2019.

Only active repositories have been included, not including forks or ‘spam’ projects. The package ecosystems analyzed are Composer, Maven, npm, NuGet, PyPi, and RubyGems.

In comparison to 2019, GitHub found that 94% of projects now rely on open source components, with close to 700 dependencies on average. Most frequently, open source dependencies are found in JavaScript — 94% — as well as Ruby and .NET, at 90%, respectively.

On average, vulnerabilities can go undetected for over four years in open source projects before disclosure. A fix is then usually available in just over a month, which GitHub says “indicates clear opportunities to improve vulnerability detection.”

Open source means that the code is available for security evaluation, not that it necessarily has been evaluated by anyone. This is an important distinction.

Amazon EKS Distro: The Kubernetes Distribution Used by Amazon EKS

Post Syndicated from Martin Beeby original https://aws.amazon.com/blogs/aws/amazon-eks-distro-the-kubernetes-distribution-used-by-amazon-eks/

Our customers have told us that they want to focus on building innovative solutions for their customers, and focus less on the heavy lifting of managing Kubernetes infrastructure. That is why Amazon Elastic Kubernetes Service (EKS) has been so popular; we remove the burden of managing Kubernetes while our customers glean the benefits.

However, not all customers choose to use Amazon EKS. For example, they may have existing infrastructure investments, data residency requirements or compliance obligations that lead them to operate Kubernetes on-premises. Customers in these situations tell us that they spend a lot of effort to track updates, figure out compatible versions of Kubernetes and the complicated matrix of underlying components, test them for compatibility, and keep pace with the Kubernetes release cadence, which can be as frequent as every three to four months. If customers are not able to maintain pace for testing and qualifying new versions, they risk breaking changes, version compatibility issues, and running unsupported versions of Kubernetes lacking critical security patches.

We have learned a lot while providing Amazon EKS at AWS and have developed a deep understanding of how to deliver Kubernetes with operational security, stability, and reliability. Today we are sharing Amazon EKS Distro, which we built using that knowledge.

EKS Distro is a distribution of the same version of Kubernetes deployed by Amazon EKS, which you can use to manually create your own Kubernetes clusters anywhere you choose. EKS Distro provides the installable builds and code of open source Kubernetes used by Amazon EKS, including the dependencies and AWS-maintained patches. Using a choice of cluster creation and management tooling, you can create EKS Distro clusters in AWS on Amazon Elastic Compute Cloud (EC2), in other clouds, and on your on-premises hardware.

EKS Distro includes upstream open source Kubernetes components and third-party tools including configuration database, network, and storage components necessary for cluster creation. They include Kubernetes control plane components (kube-controller-manager, etcd, and CoreDNS) and Kubernetes worker node components (kubelet, CNI plugins, CSI Sidecar images, Metrics Server and AWS-IAM-authenticator).

Building a Cluster
The EKS Distro repository has everything you need to build and create Kubernetes clusters. The repository contains the raw documentation for EKS Distro, and it has been built and published at https://distro.eks.amazonaws.com.

To create a new cluster, I follow this section of the documentation. The guide explains how I can build all of the parts and ultimately deploy a cluster to some EC2 instances on AWS using the open source tool kOps. EKS Distro works with many other tools besides kOps. You can find the details in the partner section of the documentation, and many partners have released blogs today that explain how you can deploy using their tooling.

The guide explains that before I can build my cluster, I need to get several container images. I can get them from the EKS Distro Container repository, download them as a tarball, or build them from scratch. I opt to build my containers from scratch and follow the Build Guide. An hour later, I have managed to create twenty containers and have pushed them into Amazon Elastic Container Registry.

The instructions detail several prerequisites that are required by both the build and deploy stages. I follow the guide and install all of the tools suggested.

Next, as per the guide, I locate the kops.sh script in the development folder of the EKS Distro repository. After running the script, it prompts me to enter a Fully Qualified Domain Name (FQDN). I provide newsblog.thebeebs.net.

This script does several things, including creating an S3 bucket in my account to store artifacts required by kOps. Also, it creates a file called newsblog.thebeebs.net.yaml. I edit this file and replace the container Image URLs with ones that point to my images in Elastic Container Registry.

I continue to follow the guide, which now instructs me to run some kOps commands to create my cluster. These commands use the newsblog.thebeebs.net.yaml file, which was an output of the previous step.

CLUSTER_NAME=newsblog.thebeebs.net
kops create -f ./$CLUSTER_NAME.yaml
kops create secret --name $CLUSTER_NAME sshpublickey admin -i ~/.ssh/id_rsa.pub
kops update cluster $CLUSTER_NAME --yes
kops validate cluster --wait 10m
cat << EOF > aws-iam-authenticator.yaml
apiVersion: v1
kind: ConfigMap
metadata:
  name: aws-iam-authenticator
  namespace: kube-system
  labels:
    k8s-app: aws-iam-authenticator
data:
  config.yaml: |
    clusterID: $CLUSTER_NAME
EOF

One of these commands creates a file called aws-iam-authenticator.yaml. I will apply this file to my kubernetes cluster so that it works correctly with the aws-iam-authenticator.

kubectl apply -f aws-iam-authenticator.yaml

I can now verify that my Kubernetes cluster is using the EKS Distro images by using kubectl to list all of the namespaces.

kubectl get po --all-namespaces -o json | jq -r .items[].spec.containers[].image | sort

Lastly, I delete my cluster by using kOps and issuing a delete command.

kops delete -f ./newsblog.thebeebs.net.yaml --yes

Updates
New versions of EKS Distro will be released soon after we make releases to Amazon EKS. The source code, open source tools, and settings are provided for reproducible builds so you can be assured EKS Distro matches what is deployed by Amazon EKS.

Things to Know
EKS Distro supports the same versions of Kubernetes and point releases that Amazon EKS uses. EKS Distro provides the same upstream versions of Kubernetes and dependencies that operating system vendors have tested and confirmed work with Kubernetes. This means that EKS Distro already works with common operating systems, such as CentOS, Canonical Ubuntu, Red Hat Enterprise Linux, Suse, and more.

Pricing and Support
EKS Distro is an open source project and will be distributed for free. Please collaborate with us on GitHub to make it even better. For example, if you find any issues, please submit them or create a pull request and we will fix them on a best effort basis. Partners will receive support through the Amazon Partner Network program and customers that adopt EKS Distro through partners will receive support from those providers.

What is Coming Next?
In 2021 we will be launching EKS Anywhere, which will provide an installable software package for creating and operating Kubernetes clusters on-premises and automation tooling for cluster lifecycle support, it will enable you to centrally backup, recover, patch, and upgrade your production clusters with minimal disruption. EKS Anywhere creates clusters based on EKS Distro, and so you will have version consistency with Amazon EKS. This version and tooling consistency will reduce support costs, and eliminate the redundant effort of using multiple tools for managing your on-premises and Amazon EKS clusters.

Available Now
EKS Distro is available today for download and you can get the source and builds from GitHub. To help you get started, check out the documentation.

Happy Deploying!

— Martin