Tag Archives: Security, Identity & Compliance

How to use the Secrets Store CSI Driver provider Amazon EKS add-on with Secrets Manager

Post Syndicated from Angad Misra original https://aws.amazon.com/blogs/security/how-to-use-the-secrets-store-csi-driver-provider-amazon-eks-add-on-with-secrets-manager/

In this post, we introduce the AWS provider for the Secrets Store CSI Driver, a new AWS Secrets Manager add-on for Amazon Elastic Kubernetes Service (Amazon EKS) that you can use to fetch secrets from Secrets Manager and parameters from AWS Systems Manager Parameter Store and mount them as files in Kubernetes pods. The add-on is straightforward to install and configure, works on Amazon Elastic Compute Cloud (Amazon EC2) instances and hybrid nodes, and includes the latest security updates and bugfixes. It provides a secure and reliable way to retrieve your secrets in Kubernetes workloads.

The AWS provider for the Secrets Store CSI Driver is an open source Kubernetes DaemonSet.

Amazon EKS add-ons provide installation and management of a curated set of add-ons for EKS clusters. You can use these add-ons to help ensure that your EKS clusters are secure and stable and reduce the number of steps required to install, configure, and update add-ons.

Secrets Manager helps you manage, retrieve, and rotate database credentials, application credentials, OAuth tokens, API keys, and other secrets throughout their lifecycles. By using Secrets Manager to store credentials, you can avoid using hard-coded credentials in application source code, helping to avoid unintended or inadvertent access.

New EKS add-on: AWS provider for the Secrets Store CSI Driver

We recommend installing the provider as an Amazon EKS add-on instead of the legacy installation methods (Helm, kubectl) to reduce the amount of time it takes to install and configure the provider. The add-on can be installed in several ways: using eksctl—which you will use in this post—the AWS Management Console, the Amazon EKS API, AWS CloudFormation, or the AWS Command Line Interface (AWS CLI).

Security considerations

The open-source Secrets Store CSI Driver maintained by the Kubernetes community enables mounting secrets as files in Kubernetes clusters. The AWS provider relies on the CSI driver and mounts secrets as file in your EKS clusters. Security best practice recommends caching secrets in memory where possible. If you prefer to adopt the native Kubernetes experience, please follow the steps in this blog post. If you prefer to cache secrets in memory, we recommend using the AWS Secrets Manager Agent.

IAM principals require Secrets Manager permissions to get and describe secrets. If using Systems Manager Parameter Store, principals also require Parameter Store permissions to get parameters. Resource policies on secrets serve as another access control mechanism, and AWS principals must be explicitly granted permissions to access individual secrets if they’re accessing secrets from a different AWS account (see Access AWS Secrets Manager secrets from a different account). The Amazon EKS add-on provides security features including support for using FIPS endpoints. AWS provides a managed IAM policy, AWSSecretsManagerClientReadOnlyAccess, which we recommend using with the EKS add-on.

Solution walkthrough

In the following sections, you’ll create an EKS cluster, create a test secret in Secrets Manager, install the Amazon EKS add-on, and use it to retrieve the test secret and mount it as a file in your cluster.

Prerequisites

  1. AWS credentials, which must be configured in your environment to allow AWS API calls and are required to allow access to Secrets Manager
  2. AWS CLI v2 or higher
  3. Your preferred AWS Region must be available in your environment. Use the following command to set your preferred region:
    aws configure set default.region <preferred_region>
    

  4. The kubectl and eksctl command-line tools
  5. A Kubernetes deployment file hosted in the GitHub repo for the provider

With the prerequisites in place, you’re ready to run the commands in the following steps in your terminal:

Create an EKS cluster

  1. Create a shell variable in your terminal with the name of your cluster:
    CLUSTER_NAME="my-test-cluster”
    

  2. Create an EKS cluster:
    eksctl create cluster $CLUSTER_NAME 
    

eksctl will automatically use a recent version of Kubernetes and create the resources needed for the cluster to function. This command typically takes about 15 minutes to finish setting up the cluster.

Create a test secret

Create a secret named addon_secret in Secrets Manager:

aws secretsmanager create-secret \
  --name addon_secret \
  --secret-string "super secret!"

Set up the Secrets Store CSI Driver provider EKS add-on

Install the Amazon EKS add-on:

eksctl create addon \
  --cluster $CLUSTER_NAME \
  --name aws-secrets-store-csi-driver-provider

Create an IAM role

Create an AWS Identity and Access Management (IAM) role that the EKS Pod Identity service principal can assume and save it in a shell variable (replace <region> with the AWS Region configured in your environment):

ROLE_ARN=$(aws --region <region> --query Role.Arn --output text iam create-role --role-name nginx-deployment-role --assume-role-policy-document '{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Service": "pods.eks.amazonaws.com"
            },
            "Action": [
                "sts:AssumeRole",
                "sts:TagSession"
            ]
        }
    ]
}')

Attach a managed policy to the IAM role

Note: AWS provides a managed policy for client-side consumption of secrets through Secrets Manager: AWSSecretsManagerClientReadOnlyAccess. This policy grants access to get and describe secrets for the secrets in your account. If you want to further follow the principle of least privilege, create a custom policy scoped down to only the secrets you want to retrieve.

Attach the managed policy to the IAM role that you just created:

aws iam attach-role-policy \
  --role-name nginx-deployment-role \
  --policy-arn arn:aws:iam::aws:policy/AWSSecretsManagerClientReadOnlyAccess

Set up the EKS Pod Identity Agent

Note: The add-on provides two methods of authentication: IAM roles for service accounts (IRSA) and EKS Pod Identity. In this solution, you’ll use EKS Pod Identity.

  1. After you’ve installed the add-on in your cluster, install the EKS Pod Identity Agent add-on for authentication:
    eksctl create addon \
      --cluster $CLUSTER_NAME \
      --name eks-pod-identity-agent
    

  2. Create an EKS Pod Identity association for the cluster:
    eksctl create podidentityassociation \
        --cluster $CLUSTER_NAME \
        --namespace default \
        --region <region> \
        --service-account-name nginx-pod-identity-deployment-sa \
        --role-arn $ROLE_ARN \
        --create-service-account true
    

Set up your SecretProviderClass

The SecretProviderClass is a YAML file that defines which secrets and parameters to mount as files in your cluster.

  1. Create a minimal SecretProviderClass called spc.yaml for the test secret with the following content:
    apiVersion: secrets-store.csi.x-k8s.io/v1
    kind: SecretProviderClass
    metadata:
      name: nginx-pod-identity-deployment-aws-secrets
    spec:
      provider: aws
      parameters:
        objects: |
          - objectName: "addon_secret"
            objectType: "secretsmanager"
        usePodIdentity: "true"
    

  2. Deploy your SecretProviderClass (make sure you’re in the same directory as the spc.yaml you just created):
    kubectl apply -f spc.yaml
    

To learn more about the SecretProviderClass, see the GitHub readme for the provider.

Deploy your pod to your EKS cluster

For brevity, we’ve omitted the content of the Kubernetes deployment file. The following is an example deployment file for Pod Identity in the GitHub repository for the provider—use this file to deploy your pod:

kubectl apply -f https://raw.githubusercontent.com/aws/secrets-store-csi-driver-provider-aws/main/examples/ExampleDeployment-PodIdentity.yaml

This will mount addon_secret at /mnt/secrets-store in your cluster.

Retrieve your secret

  1. Print the value of addon_secret to confirm that the secret was mounted successfully:
    kubectl exec -it $(kubectl get pods | awk '/nginx-pod-identity-deployment/{print $1}' | head -1) -- cat /mnt/secrets-store/addon_secret
    

  2. You should see the following output:
    super secret!
    

You’ve successfully fetched your test secret from Secrets Manager using the new Amazon EKS add-on and mounted it as a file in your Kubernetes cluster.

Clean up

Run the following commands to clean up the resources that you created in this tutorial:

aws secretsmanager delete-secret \
  --secret-id addon_secret \
  --force-delete-without-recovery

aws iam delete-role --role-name nginx-deployment-role

eksctl delete cluster $CLUSTER_NAME

Conclusion

In this post, you learned how to use the new Amazon EKS add-on for the AWS Secrets Store CSI Driver provider to securely retrieve your secrets and parameters and mount them as files in your Kubernetes clusters. The new EKS add-on provides benefits such as the latest security patches and bug fixes, tighter integration with Amazon EKS, and reduces the time it takes to install and configure the AWS Secrets Store CSI Driver provider. The add-on is validated by EKS to work with EC2 instances and hybrid nodes.

Further reading

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Angad Misra

Angad Misra

Angad is a Software Engineer on the AWS Secrets Manager team. When he isn’t building secure, reliable, and scalable software from first principles, he enjoys a good latte, live music, playing guitar, exploring the great outdoors, cooking, and lazing around with his cat, Freyja.

AWS Secrets Manager launches Managed External Secrets for Third-Party Credentials

Post Syndicated from Rohit Panjala original https://aws.amazon.com/blogs/security/aws-secrets-manager-launches-managed-external-secrets-for-third-party-credentials/

Although AWS Secrets Manager excels at managing the lifecycle of Amazon Web Services (AWS) secrets, managing credentials from third-party software providers presents unique challenges for organizations as they scale usage of their cloud applications. Organizations using multiple third-party services frequently develop different security approaches for each provider’s credentials because there hasn’t been a standardized way to manage them. When storing these third-party credentials in Secrets Manager, organizations frequently maintain additional metadata within secret values to facilitate service connections. This approach requires updating entire secret values when metadata changes and implementing provider-specific secret rotation processes that are manual and time consuming. Organizations looking to automate secret rotation typically develop custom functions tailored to each third-party software provider, requiring specialized knowledge of both third-party and AWS systems.

To help customers streamline third-party secrets management, we’re introducing a new feature in AWS Secrets Manager called managed external secrets. In this post, we explore how this new feature simplifies the management and rotation of third-party software credentials while maintaining security best practices.

Introducing managed external secrets

AWS Secrets Manager has a proven track record of helping customers secure and manage secrets for AWS services such as Amazon Relational Database Service (Amazon RDS) or Amazon DocumentDB through managed rotation capabilities. Building on this success, Secrets Manager now introduces managed external secrets, a new secret type that extends this same seamless experience to third-party software applications like Salesforce, simplifying secret management challenges through standardized formats and automated rotation.

You can use this capability to store secrets vended by third-party software providers in predefined formats. These formats were developed in collaboration with trusted integration partners to define both the secret structure and required metadata for rotation, eliminating the need for you to define your own custom storage strategies. Managed external secrets also provides automated rotation by directly integrating with software providers. With no rotation functions to maintain, you can reduce your operational overhead while benefiting from essential security controls, including fine-grained permissions management using AWS Identity and Access Management (IAM), secret access monitoring through Amazon CloudWatch and AWS CloudTrail, and automated secret-specific threat detection through Amazon GuardDuty. Moreover, you can implement centralized and consistent secret management practices across both AWS and third-party secrets from a single service, eliminating the need to operate multiple secrets management solutions at your organization. Managed external secrets follows standard Secrets Manager pricing, with no additional cost for using this new secret type.

Prerequisites

To create a managed external secret, you need an active AWS account with appropriate access to Secrets Manager. The account must have sufficient permissions to create and manage secrets, including the ability to access the AWS Management Console or programmatic access through the AWS Command Line Interface (AWS CLI) or AWS SDKs. At minimum, you need IAM permissions for the following actions: secretsmanager:DescribeSecret, secretsmanager:GetSecretValue, secretsmanager:UpdateSecret, and secretsmanager:UpdateSecretVersionStage.

You must have valid credentials and necessary access permissions for the third-party software provider you plan to have AWS manage secrets for.

For secret encryption, you must decide whether to use an AWS managed AWS Key Management Service (AWS KMS) key or a customer managed KMS key. For customer managed keys, make sure you have the necessary key policies configured. The AWS KMS key policy should allow Secrets Manager to use the key for encryption and decryption operations.

Create a managed external secret

Today, managed external secrets supports three integration partners: Salesforce, Snowflake, and BigID. Secrets Manager will continue to expand its partner list and more third-party software providers will be added over time. For the latest list, refer to Integration Partners.

To create a managed external secret, follow the steps in the following sections.

Note: This example demonstrates the steps for retrieving Salesforce External Client App Credentials, but a similar process can be followed for other third-party vendor credentials integrated with Secrets Manager.

To select secret type and add details:

  1. Go to the Secrets Manager service in the AWS Management Console and choose Store a new secret.
  2. Under Secret type, select Managed external secret.
  3. In the AWS Secrets Manager integrated third-party vendor credential section, select your provider from the available options. For this walkthrough, we select Salesforce External Client App Credential.
  4. Enter your configurations in the Salesforce External Client App Credential secret details section. The Salesforce External Client App credentials consist of several key components:
    1. The Consumer key (client ID), which serves as the credential identifier for OAuth 2.0. You can retrieve the consumer key directly from the Salesforce External Client App Manager OAuth settings.
    2. The Consumer secret (client secret), which functions as the private password for OAuth 2.0 authentication. You can retrieve the consumer secret directly from the Salesforce External Client App Manager OAuth settings.
    3. The Base URI, which is your Salesforce org’s base URL (formatted as https://MyDomainName.my.salesforce.com), is used to interact with Salesforce APIs.
    4. The App ID, which identifies your Salesforce External Client Apps (ECAs) and can be retrieved by calling the Salesforce OAuth usage endpoint.
    5. The Consumer ID, which identifies your Salesforce ECA, can be retrieved by calling the Salesforce OAuth credentials by App ID endpoint. For a list of commands, refer to Stage, Rotate, and Delete OAuth Credentials for an External Client App in the Salesforce documentation.
  5. Select the Encryption key from the dropdown menu. You can use an AWS managed KMS key or a customer managed KMS key.
  6. Choose Next.
Figure 1: Choose secret type

Figure 1: Choose secret type

To configure a secret:

  1. In this section, you need to provide information for your secret’s configuration.
  2. In Secret name, enter a descriptive name and optionally enter a detailed Description that helps identify the secret’s purpose and usage. You also have additional configuration choices available: you can attach Tags for better resource organization, set specific Resource permissions to control access, and select Replicate secret for multi-Region resilience.
  3. Choose Next.
Figure 2: Configure secret

Figure 2: Configure secret

To configure rotation and permissions (optional):

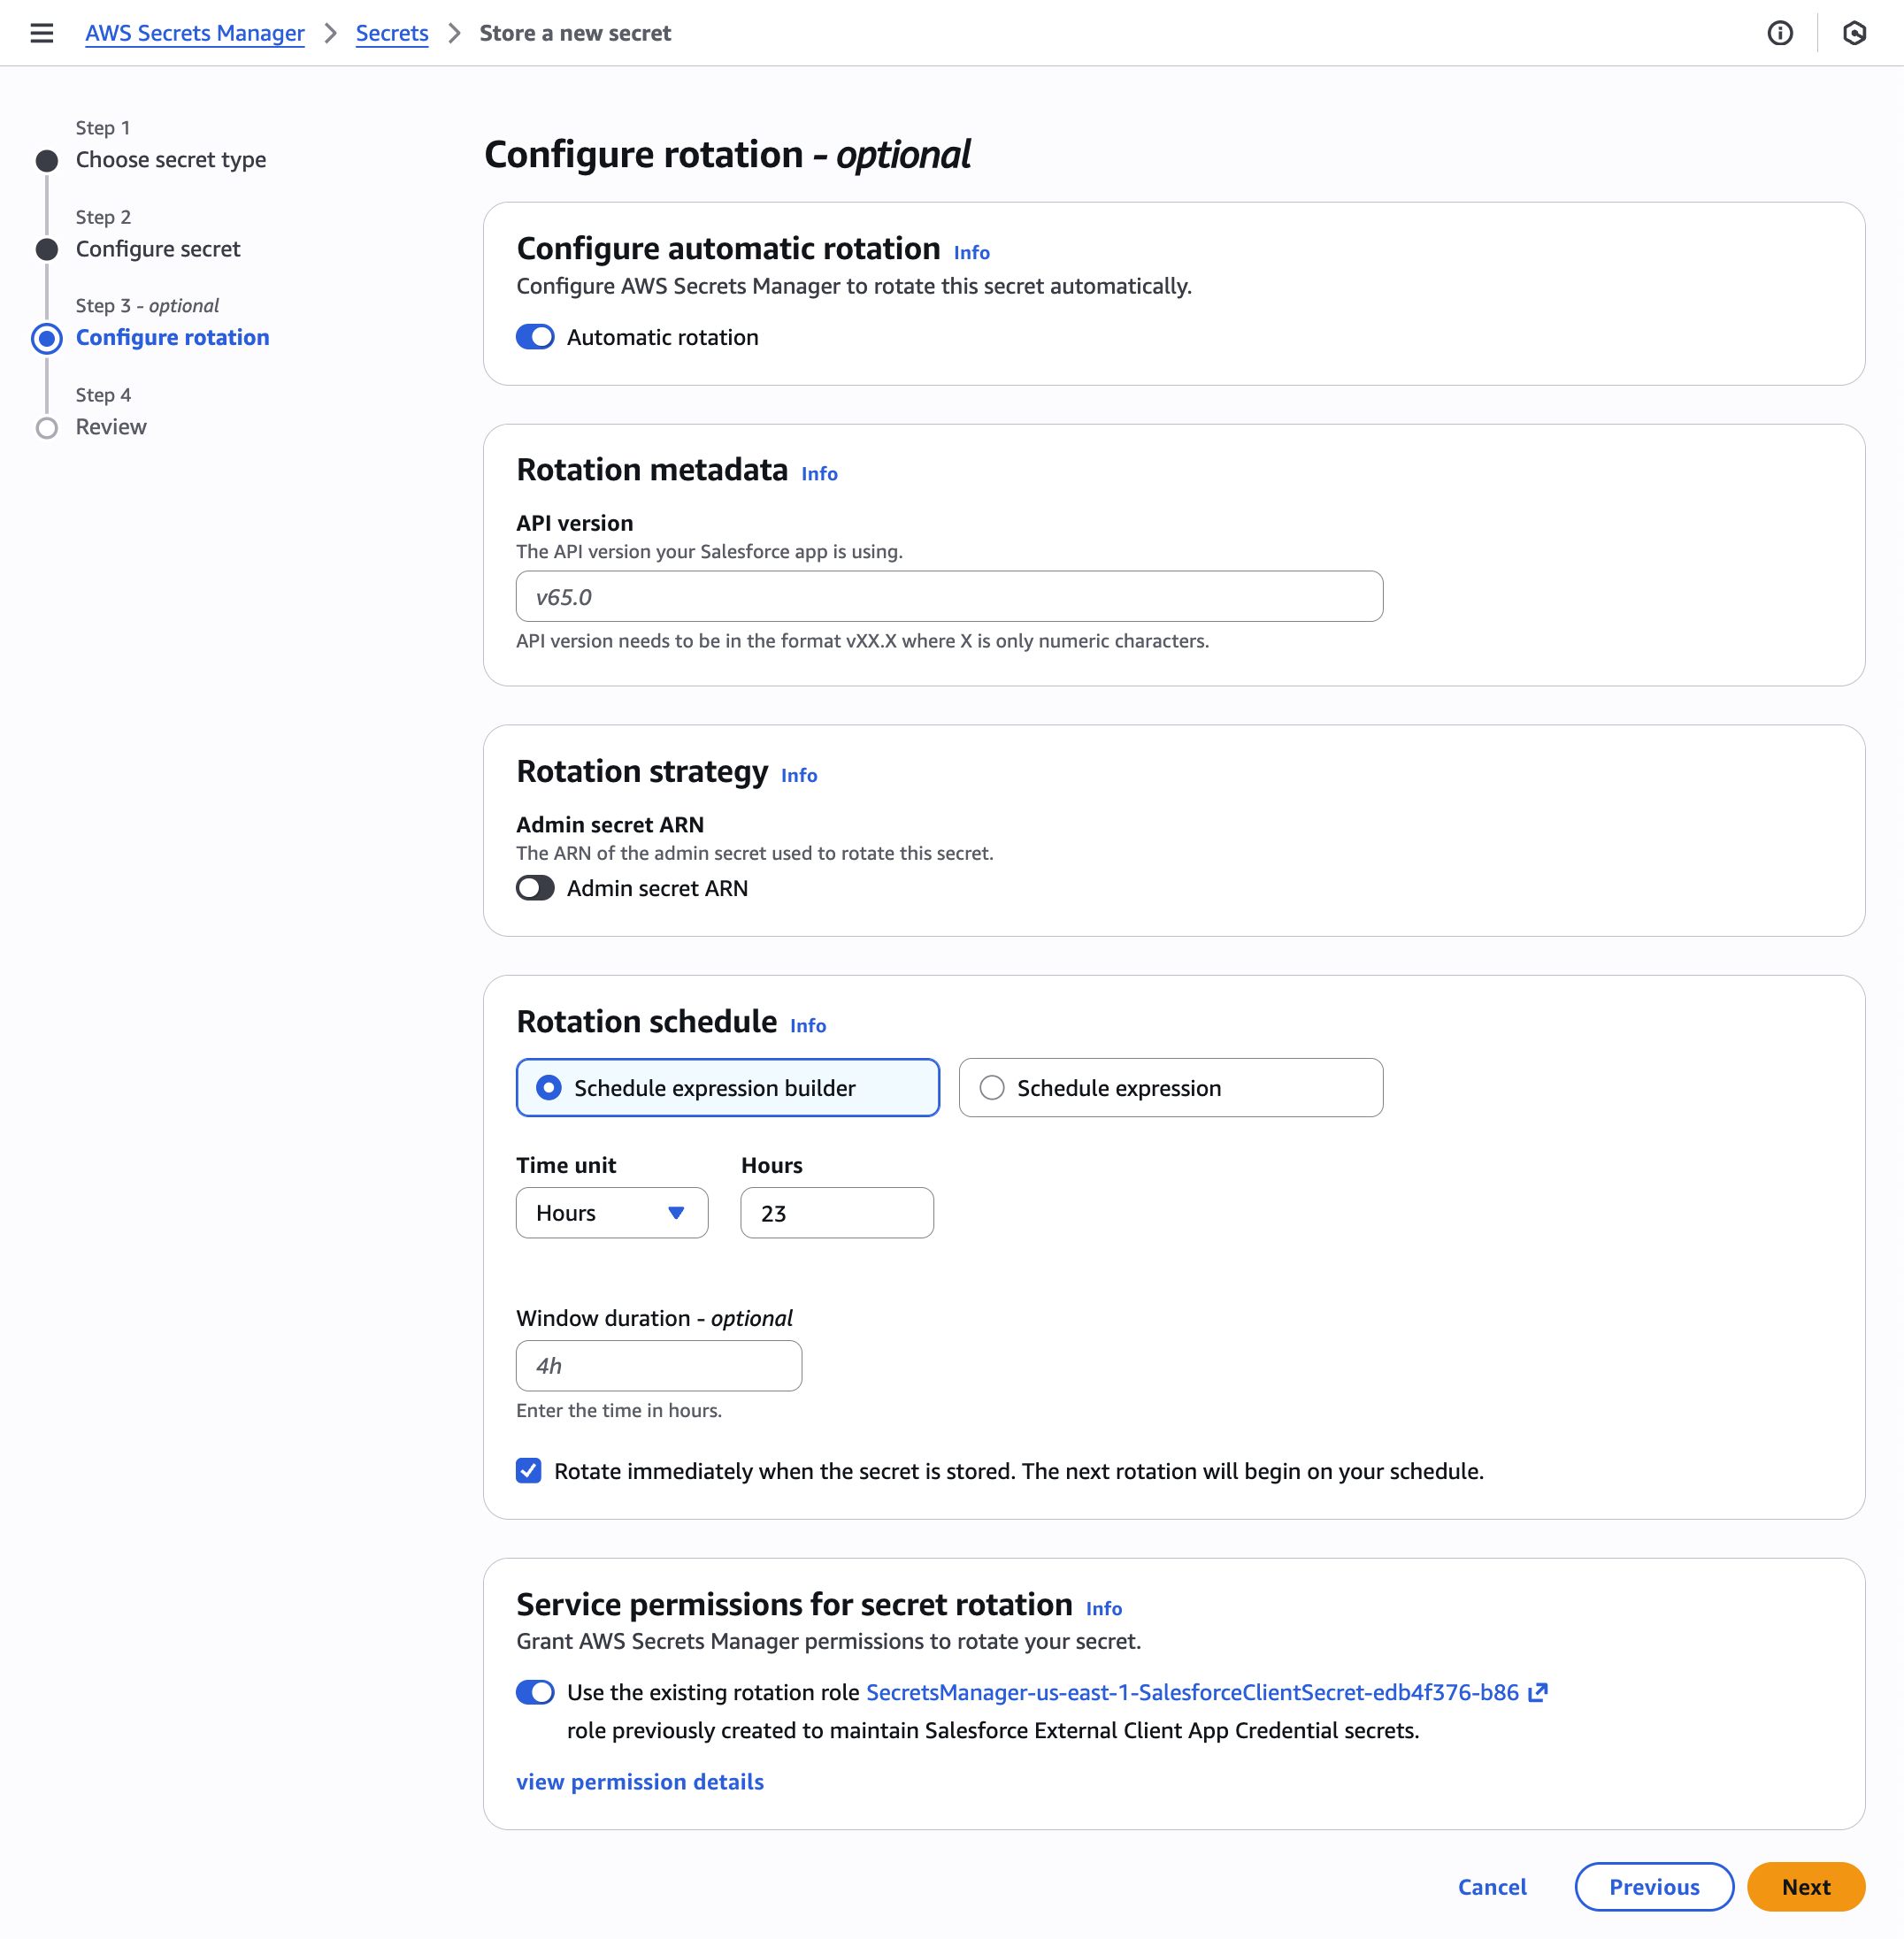
In the optional Configure rotation step, the new secret configuration introduces two key sections focused on metadata management, which are stored separately from the secret value itself.

  1. Under Rotation metadata, specify the API version your Salesforce app is using. To find the API version, refer to List Available REST API Versions in the Salesforce documentation. Note: The minimum version needed is v65.0.
  2. Select an Admin secret ARN, which contains the administrative OAuth credentials that are used to rotate the Salesforce client secret.
  3. In the Service permissions for secret rotation section, Secrets Manager automatically creates a role with necessary permissions to rotate your secret values. These default permissions are transparently displayed in the interface for review when you choose view permission details. You can deselect the default permissions for more granular control over secret rotation management.
  4. Choose Next.
Figure 3: Configure rotation

Figure 3: Configure rotation

To review:

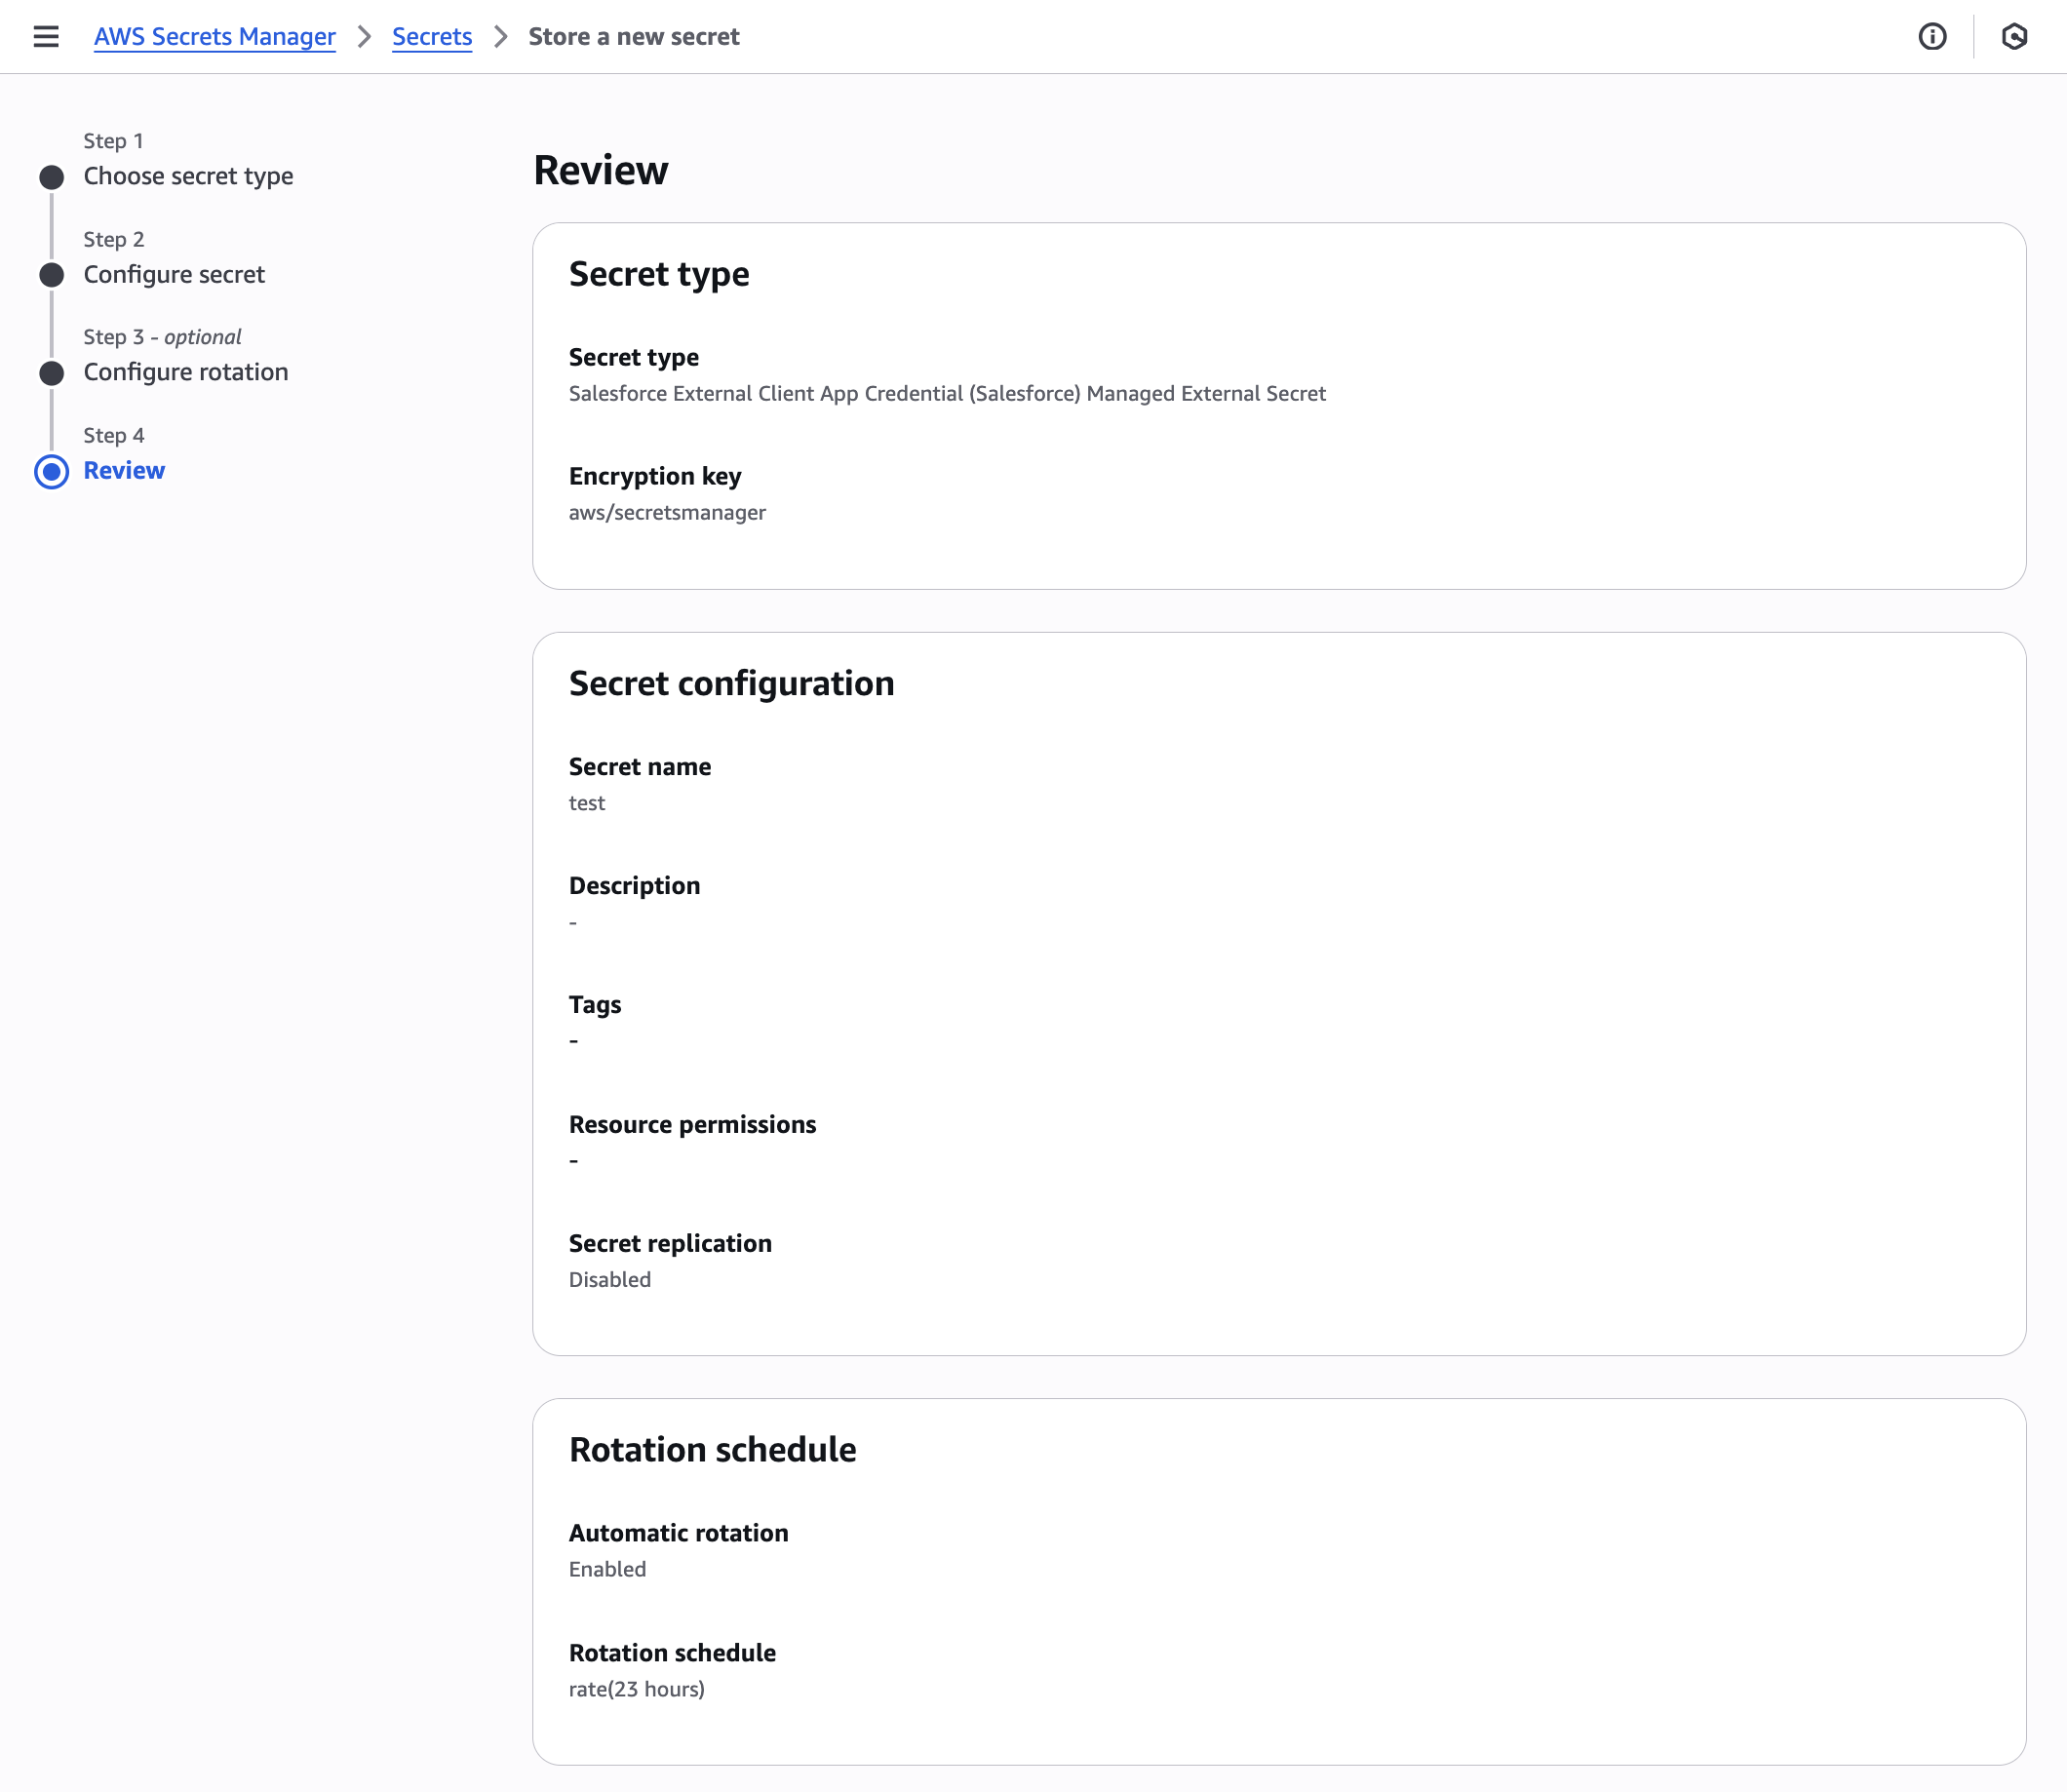
In the final step, you’ll be presented with a summary of your secret’s configuration. On the Review page, you can verify parameters before proceeding with secret creation.

After confirming that the configurations are correct, choose Store to complete the process and create your secret with the specified settings.

Figure 4: Review

Figure 4: Review

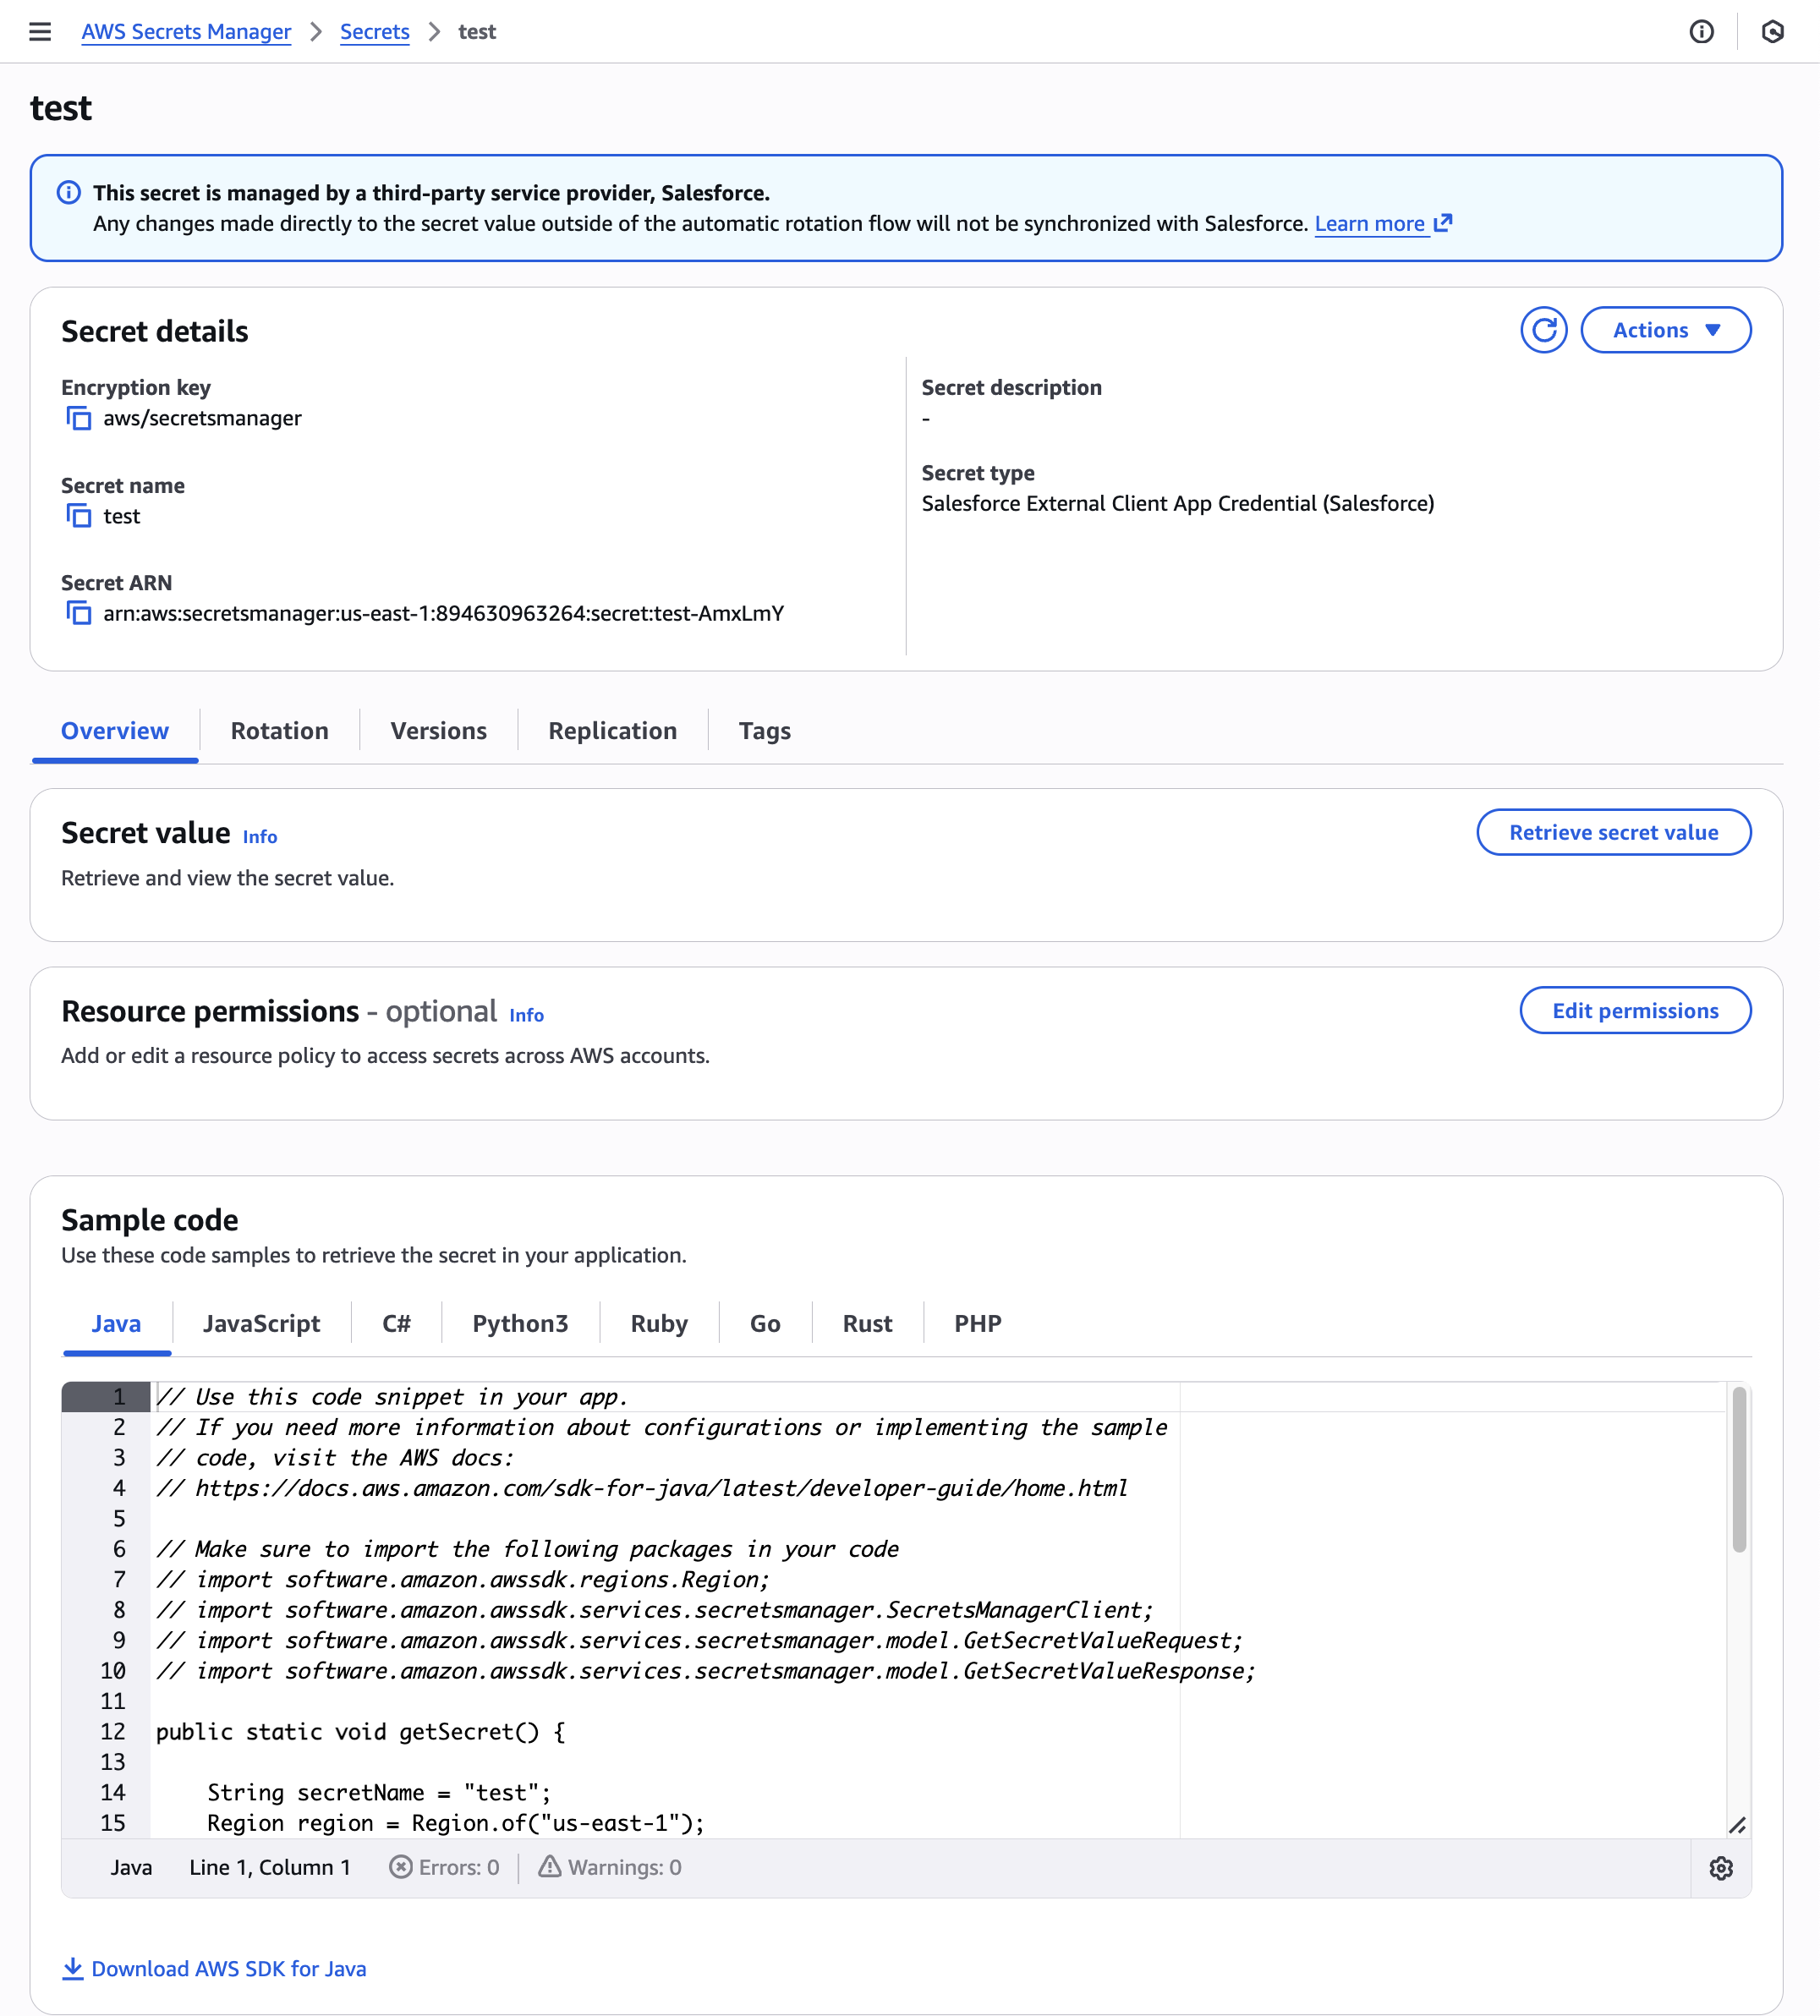
After successful creation, your secret will appear on the Secrets tab. You can view, manage, and monitor aspects of your secret, including its configuration, rotation status, and permissions. After creation, review your secret configuration, including encryption settings and resource policies for cross-account access, and examine the sample code provided for different AWS SDKs to integrate secret retrieval into your applications. The Secrets tab provides an overview of your secrets, allowing for central management of secrets. Select your secret to view Secret details.

Figure 5: View secret details

Figure 5: View secret details

Your managed external secret has been successfully created in Secrets Manager. You can access and manage this secret through the Secrets Manager console or programmatically using AWS APIs.

Onboard as an integration partner with Secrets Manager

With the new managed external secret type, third-party software providers can integrate with Secrets Manager and offer their customers a programmatic way to securely manage secrets vended by their applications on AWS. This integration provides their customers with a centralized solution for managing both the lifecycle of AWS and third-party secrets, including automatic rotation capabilities from the moment of secret creation. Software providers like Salesforce are already using this capability.

“At Salesforce, we believe security shouldn’t be a barrier to innovation, it should be an enabler. Our partnership with AWS on managed external secrets represents security-by-default in action, removing operational burden from our customers while delivering enterprise-grade protection. With AWS Secrets Manager now extending to partners and automated zero-touch rotation eliminating human risk, we’re setting a new industry standard where secure credentials become seamless without specialized expertise or additional costs.” — Jay Hurst, Sr. Vice President, Product Management at Salesforce

There is no additional cost to onboard with Secrets Manager as an integration partner. To get started, partners must follow the process listed on the partner onboarding guide. If you have questions about becoming an integration partner, contact our team at [email protected] with Subject: [Partner Name] Onboarding request.

Conclusion

In this post, we introduced managed external secrets, a new secret type in Secrets Manager that addresses the challenges of securely managing the lifecycle of third-party secrets through predefined formats and automated rotation. By eliminating the need to define custom storage strategies and develop complex rotation functions, you can now consistently manage your secrets—whether from AWS services, custom applications, or third-party providers—from a single service. Managed external secrets provide the same security features as standard Secrets Manager secrets, including fine-grained permissions management, observability, and compliance controls, while adding built-in integration with trusted partners at no additional cost.

To get started, refer to the technical documentation. For information on migrating your existing partner secrets to managed external secrets, see Migrating existing secrets. The feature is available in all AWS Regions where AWS Secrets Manager is available. For a list of Regions where Secrets Manager is available, see the AWS Region table. If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on Secrets Manager re:Post or contact AWS Support.

Rohit Panjala

Rohit is a Security Specialist at AWS, focused on data protection and cryptography services. He is responsible for developing and implementing go-to-market (GTM) strategies and driving customer and partner adoptions for AWS data protection services on a global scale. Before joining AWS, he worked in security product management at IBM and electrical engineering roles. He holds a BS in engineering from The Ohio State University.

Rochak Karki

Rochak is a Security Specialist Solutions Architect at AWS, focusing on threat detection, incident response, and data protection to help customers build secure environments. Rochak is a US Army veteran and holds a BS in engineering from the University of Wyoming. Outside of work, he enjoys spending time with family and friends, hiking, and traveling.

Introducing guidelines for network scanning

Post Syndicated from Stephen Goodman original https://aws.amazon.com/blogs/security/introducing-guidelines-for-network-scanning/

Amazon Web Services (AWS) is introducing guidelines for network scanning of customer workloads. By following these guidelines, conforming scanners will collect more accurate data, minimize abuse reports, and help improve the security of the internet for everyone.

Network scanning is a practice in modern IT environments that can be used for either legitimate security needs or abused for malicious activity. On the legitimate side, organizations conduct network scans to maintain accurate inventories of their assets, verify security configurations, and identify potential vulnerabilities or outdated software versions that require attention. Security teams, system administrators, and authorized third-party security researchers use scanning in their standard toolkit for collecting security posture data. However, scanning is also performed by threat actors attempting to enumerate systems, discover weaknesses, or gather intelligence for attacks. Distinguishing between legitimate scanning activity and potentially harmful reconnaissance is a constant challenge for security operations.

When software vulnerabilities are found through scanning a given system, it’s particularly important that the scanner is well-intentioned. If a software vulnerability is discovered and attacked by a threat actor, it could allow unauthorized access to an organization’s IT systems. Organizations must effectively manage their software vulnerabilities to protect themselves from ransomware, data theft, operational issues, and regulatory penalties. At the same time, the scale of known vulnerabilities is growing rapidly, at a rate of 21% per year for the past 10 years as reported in the NIST National Vulnerability Database.

With these factors at play, network scanners need to scan and manage the collected security data with care. There are a variety of parties interested in security data, and each group uses the data differently. If security data is discovered and abused by threat actors, then system compromises, ransomware, and denial of service can create disruption and costs for system owners. With the exponential growth of data centers and connected software workloads providing critical services across energy, manufacturing, healthcare, government, education, finance, and transportation sectors, the impact of security data in the wrong hands can have significant real-world consequences.

Multiple parties

Multiple parties have vested interests in security data, including at least the following groups:

  • Organizations want to understand their asset inventories and patch vulnerabilities quickly to protect their assets.
  • Program auditors want evidence that organizations have robust controls in place to manage their infrastructure.
  • Cyber insurance providers want risk evaluations of organizational security posture.
  • Investors performing due diligence want to understand the cyber risk profile of an organization.
  • Security researchers want to identify risks and notify organizations to take action.
  • Threat actors want to exploit unpatched vulnerabilities and weaknesses for unauthorized access.

The sensitive nature of security data creates a complex ecosystem of competing interests, where an organization must maintain different levels of data access for different parties.

Motivation for the guidelines

We’ve described both the legitimate and malicious uses of network scanning, and the different parties that have an interest in the resulting data. We’re introducing these guidelines because we need to protect our networks and our customers; and telling the difference between these parties is challenging. There’s no single standard for the identification of network scanners on the internet. As such, system owners and defenders often don’t know who is scanning their systems. Each system owner is independently responsible for managing identification of these different parties. Network scanners might use unique methods to identify themselves, such as reverse DNS, custom user agents, or dedicated network ranges. In the case of malicious actors, they might attempt to evade identification altogether. This degree of identity variance makes it difficult for system owners to know the motivation of parties performing network scanning.

To address this challenge, we’re introducing behavioral guidelines for network scanning. AWS seeks to provide network security for every customer; our goal is to screen out abusive scanning that doesn’t meet these guidelines. Parties that broadly network scan can follow these guidelines to receive more reliable data from AWS IP space. Organizations running on AWS receive a higher degree of assurance in their risk management.

When network scanning is managed according to these guidelines, it helps system owners strengthen their defenses and improve visibility across their digital ecosystem. For example, Amazon Inspector can detect software vulnerabilities and prioritize remediation efforts while conforming to these guidelines. Similarly, partners in AWS Marketplace use these guidelines to collect internet-wide signals and help organizations understand and manage cyber risk.

“When organizations have clear, data-driven visibility into their own security posture and that of their third parties, they can make faster, smarter decisions to reduce cyber risk across the ecosystem.” – Dave Casion, CTO, Bitsight

Of course, security works better together, so AWS customers can report abusive scanning to our Trust & Safety Center as type Network Activity > Port Scanning and Intrusion Attempts. Each report helps improve the collective protection against malicious use of security data.

The guidelines

To help ensure that legitimate network scanners can clearly differentiate themselves from threat actors, AWS offers the following guidance for scanning customer workloads. This guidance on network scanning complements the policies on penetration testing and vulnerability reporting. AWS reserves the right to limit or block traffic that appears non-compliant with these guidelines. A conforming scanner adheres to the following practices:

Observational

  • Perform no actions that attempt to create, modify, or delete resources or data on discovered endpoints.
  • Respect the integrity of targeted systems. Scans cause no degradation to system function and cause no change in system configuration.
  • Examples of non-mutating scanning include:
    • Initiating and completing a TCP handshake
    • Retrieving the banner from an SSH service

Identifiable

  • Provide transparency by publishing sources of scanning activity.
  • Implement a verifiable process for confirming the authenticity of scanning activities.
  • Examples of identifiable scanning include:
    • Supporting reverse DNS lookups to one of your organization’s public DNS zones for scanning Ips.
    • Publishing scanning IP ranges, organized by types of requests (such as service existence, vulnerability checks).
    • If HTTP scanning, have meaningful content in user agent strings (such as names from your public DNS zones, URL for opt-out)

Cooperative

  • Limit scan rates to minimize impact on target systems.
  • Provide an opt-out mechanism for verified resource owners to request cessation of scanning activity.
  • Honor opt-out requests within a reasonable response period.
  • Examples of cooperative scanning include:
    • Limit scanning to one service transaction per second per destination service.
    • Respect site settings as expressed in robots.txt and security.txt and other such industry standards for expressing site owner intent.

Confidential

  • Maintain secure infrastructure and data handling practices as reflected by industry-standard certifications such as SOC2.
  • Ensure no unauthenticated or unauthorized access to collected scan data.
  • Implement user identification and verification processes.

See the full guidance on AWS.

What’s next?

As more network scanners follow this guidance, system owners will benefit from reduced risk to their confidentiality, integrity, and availability. Legitimate network scanners will send a clear signal of their intention and improve their visibility quality. With the constantly changing state of networking, we expect that this guidance will evolve along with technical controls over time. We look forward to input from customers, system owners, network scanners and others to continue improving security posture across AWS and the internet.

If you have feedback about this post, submit comments in the Comments section below or contact AWS Support.

Stephen Goodman

Stephen Goodman

As a senior manager for Amazon active defense, Stephen leads data-driven programs to protect AWS customers and the internet from threat actors.

Practical steps to minimize key exposure using AWS Security Services

Post Syndicated from Jennifer Paz original https://aws.amazon.com/blogs/security/practical-steps-to-minimize-key-exposure-using-aws-security-services/

Exposed long-term credentials continue to be the top entry point used by threat actors in security incidents observed by the AWS Customer Incident Response Team (CIRT). The exposure and subsequent use of long-term credentials or access keys by threat actors poses security risks in cloud environments. Additionally, poor key rotation practices, sharing of access keys among multiple users, or failing to revoke unused credentials can leave systems exposed.

Using long-term credentials is strongly discouraged and presents an opportunity to migrate towards AWS Identity and Access Management (IAM) roles and federated access. While our recommended best practice is for customers to migrate away from long-term credentials, we recognize that this transition might not be immediately feasible for all organizations.

Building a comprehensive defense against unintended access to long-term credentials requires a strategic layered approach. This approach is intended to bridge the gap between ideal security practices and real-world operational constraints, providing actionable steps for teams managing legacy AWS workloads that require the use of long-term credentials.

In this post, you learn how to build your defense, starting with identifying existing risks and potential exposures through services such as Amazon CodeGuru Security and AWS IAM Access Analyzer, providing visibility into credential risks across the environment. This is then complemented by establishing strict boundaries through service control policies (SCPs) and data perimeters to control how and where credentials can be created and used. With these mechanisms in place, you can strengthen your position with network-level controls that help protect the infrastructure where access keys might be used, implementing services such as AWS WAF and Amazon Inspector to help protect against exploitation of vulnerabilities. Finally, you implement operational best practices such as automated secret rotation to maintain ongoing security hygiene and minimize the impact of potential compromise.

Detect current access keys and exposure

Audit current access keys

For comprehensive auditing, organizations should regularly generate credential reports to identify IAM user ownership of long-lived credentials and other relevant information such as the last time the key was rotated, last time it was used, last service used and last region used. These reports provide essential visibility into your credential landscape, enabling you to spot unused or potentially compromised credentials by focusing on access keys with stale activity, keys exceeding rotation policies, and unexpected usage patterns from unfamiliar regions.

Detect exposed access keys

A common source of credential compromise occurs through inadvertent commits to public repositories. When developers accidentally commit credentials to public repositories, these credentials can be harvested by automated scanning tools used by adversaries. Code scanning is a foundational step that helps catch these critical security issues early, before sensitive credentials can be accidentally committed to code repositories or deployed to production environments where they could be exploited.

You can use the secrets detection capability of CodeGuru Security to proactively identify exposed sensitive data in your codebase.

The tool integrates with AWS Secrets Manager, employing detection mechanisms to locate unencrypted secrets in your code, such as AWS secret access keys, embedded passwords, and database connection strings.

When CodeGuru Security discovers unprotected secrets during a scan, it creates a finding with recommended remediation to address the vulnerability.

AWS Trusted Advisor also contains an exposed access key check that checks popular code repositories for access keys that have been exposed to the public and for irregular Amazon Elastic Compute Cloud (Amazon EC2) usage that could be the result of a compromised access key.

Note that while these are valuable security tools, they cannot detect secrets or access keys stored in locations outside their scanning scope, such as local development machines or external systems. They should be used as part of a broader security strategy, not as the sole method for identifying and preventing credential exposure.

When addressing potentially compromised access keys, it is advised to immediately rotate the keys. See instructions on how to rotate access keys for IAM Users.

Detect unused access

Beyond identifying exposed credentials, detecting unused access keys helps minimize the attack surface. IAM Access Analyzer contains an unused access analyzer that looks for access permissions that are either overly generous or that have fallen into disuse, including unused IAM roles, access keys for IAM users, passwords for IAM users, and services and actions for active IAM roles and users. After reviewing the findings generated by an organization-wide or account-specific analyzer, you can remove or modify permissions that aren’t needed. By identifying and revoking unused credentials and access, you can limit the impact if credentials have been obtained by a threat actor.

By implementing these tools, you can gain insights into credential risks across your environment. The combined capabilities help surface embedded secrets, exposed access keys, and credentials requiring removal.

Preventive guardrails: Establish a data perimeter

Now that you’ve learned how to identify exposed or unused credentials, let’s explore how you can use SCPs and resource control policies (RCPs) to create a data perimeter and help make sure that only your trusted identities are accessing trusted resources from expected networks. Implementing preventive guardrails around your AWS environment is crucial for helping protect against unauthorized access and potential access key compromises. For more information on what a data perimeter is and how to establish one, see the Establishing a Data Perimeter on AWS blog post series.

The following SCP denies an IAM user’s credentials from being used outside of unexpected networks (corporate Classless Inter-Domain Routing (CIDR) or specific virtual private cloud (VPC)). This policy includes several actions in the NotAction element that would impact services access if not exempted. Examples of SCPs and RCPs can be found in the data-perimeter-policy-examples, which is the source of truth for newly revised policies. The following example has been updated to address the use case of user credentials being used outside of unexpected networks.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "EnforceNetworkPerimeterOnIAMUsers",
            "Effect": "Deny",
            "NotAction": [
                "es:ES*",
                "dax:GetItem",
                "dax:BatchGetItem",
                "dax:Query",
                "dax:Scan",
                "dax:PutItem",
                "dax:UpdateItem",
                "dax:DeleteItem",
                "dax:BatchWriteItem",
                "dax:ConditionCheckItem",
                "neptune-db:*",
                "kafka-cluster:*",
                "elasticfilesystem:client*",
                "rds-db:connect"
            ],
            "Resource": "*",
            "Condition": {
                "BoolIfExists": {
                    "aws:ViaAWSService": "false"
                },
                "NotIpAddressIfExists": {
                    "aws:SourceIp": [
                        "<my-corporate-cidr>"
                    ]
                },
                "StringNotEqualsIfExists": {
                    "aws:SourceVpc": [
                        "<my-vpc>"
                    ]
                },
                "ArnLike": {
                    "aws:PrincipalArn": [
                        "arn:aws:iam::*:user/*"
                    ]
                }
            }
        }
    ]

By implementing this network perimeter, you can reduce the risk of credential compromise leading to unauthorized access and data exposure. Threat actors attempting to use stolen credentials from a coffee shop or home network will be blocked, helping to limit the impact of unintended access to credentials.

To further increase your defense in depth, you can use RCPs to help protect your data, such as by using them to control which identities can access your resources. For example, you might want to allow identities in your organization to access resources in your organization. You might also want to prevent identities external to your organization from accessing your resources. You can enforce this control using RCPs. You can use RCPs to restrict the maximum available access to your resources and include which principals, both inside and outside your organization, can access your resources. SCPs can only impact the effective permissions for principals within your AWS organization.

By implementing the following RCP, you can help make sure that if long-lived credentials are accidentally exposed, unauthorized users from outside your organization will be blocked from using them to access your critical data and resources. The policy will deny Amazon Simple Storage Service (Amazon S3) actions unless requested from your corporate CIDR range (NotIpAddressIfExists with aws:SourceIp), or from your VPC (StringNotEqualsIfExists with aws:SourceVpc). See the list of AWS services that support RCPs. Examples of SCPs and RCPs can be found in this GitHub repository, which is the source of truth for newly revised policies. The following example has been updated to address the use case discussed in this post.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceNetworkPerimeter",
      "Effect": "Deny",
      "Principal": "*",
      "Action": [
		"s3:*",
		"sqs:*",
		"kms:*",
		"secretsmanager:*",
		"sts:AssumeRole",
		"sts:DecodeAuthorizationMessage",
		"sts:GetAccessKeyInfo",
		"sts:GetFederationToken",
		"sts:GetServiceBearerToken",
		"sts:GetSessionToken",
 		"sts:SetContext",
 		"aoss:*",
 		"ecr:*"
		],
      "Resource": "*",
      "Condition": {
        "NotIpAddressIfExists": {
          "aws:SourceIp": "<0.0.0.0/1>"
        },
        "StringNotEqualsIfExists": {
          "aws:SourceVpc": "<my-vpc>"
        },
        "BoolIfExists": {
          "aws:PrincipalIsAWSService": "false",
          "aws:ViaAWSService": "false"
        }
      }
	 }
    ]
  }

If you’re ready to begin migrating away from long-term credentials, using an SCP to deny access key creation and deny updates to existing keys helps enforce the use of more secure authentication methods like IAM roles and federated access. This policy denies principals from creating or updating an AWS access key.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Deny",
            "Action": [
                "iam:CreateAccessKey",
			 	"iam:UpdateAccessKey"
            ],
            "Resource": "*"
        }
    ]
}

In addition to establishing these data perimeter controls, let’s examine how network controls protect the runtime environments where access keys operate.

Network controls: Protecting the runtime environment for access keys

Beyond building a data perimeter and using SCPs and RCPs, protecting the compute and network infrastructure that uses these access keys is essential. The risk of credential exposure through compromised runtime environments makes infrastructure protection a critical component of access key security, because bad actors often target these environments to gain unauthorized access.

Security groups and network ACLs (NACLs)

Use network-level security protections that act as firewalls for varying levels, such as the instance level or the subnet level to help protect against unauthorized access.

  • Restricting critical ports, such as SSH (port 22) and RDP (port 3306), is essential because they’re prime targets for bad actors seeking unauthorized system access. Open administrative ports in your security groups can increase your attack surface and security risk. Using AWS Systems Manager Session Manager helps provide secure remote access without exposing inbound ports, alleviating the need for bastion hosts or SSH key management.
  • NACLs effectively block access at the subnet level by acting as stateless packet filters at subnet boundaries. Unlike security groups that protect individual instances, NACLs help secure entire subnets with explicit allow/deny rules for both inbound and outbound traffic. They create a critical perimeter defense layer that filters traffic before reaching your instances. When deployed as part of a defense-in-depth approach, NACLs provide subnet-level isolation between application tiers, block malicious traffic patterns at the network edge, and maintain protection even if other security layers are compromised, helping to facilitate comprehensive network security through multiple independent control points.
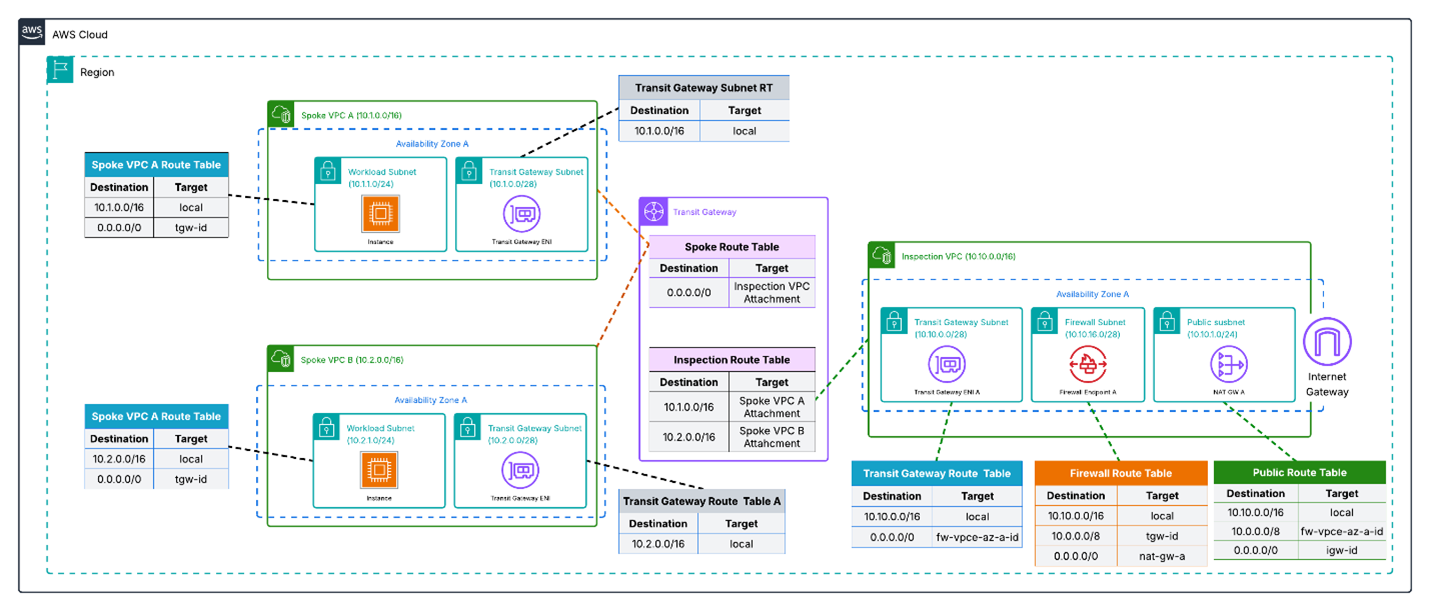
  • For enhanced network protection beyond NACLs, AWS Network Firewall enables enterprise-grade perimeter defense through comprehensive VPC protection. It combines intrusion prevention systems, domain filtering, deep packet inspection, and geographic IP controls, while automatically safeguarding your cloud environment against emerging threats using global threat intelligence gathered by Amazon. By using Network Firewall and AWS Transit Gateway integration, you can implement consistent security policies across your VPCs and Availability Zones with centralized management.
  • To automate and scale network security across your organization, AWS Firewall Manager provides centralized administration of both Network Firewall rules and security group policies. As your organization grows, Firewall Manager helps maintain security by automating the deployment of common security group policies, cleaning up unused groups, and remediating overly permissive rules across multiple accounts and organizational units.

Amazon Inspector

To help identify unintended network exposure at scale, consider using Amazon Inspector. Amazon Inspector continually scans AWS workloads for software vulnerabilities and unintended network exposure, helping you identify and remediate security vulnerabilities before they can be exploited.

Key capabilities include:

  • Package vulnerability: Package vulnerability findings identify software packages in your AWS environment that are exposed to Common Vulnerabilities and Exposures (CVEs). Bad actors can exploit these unpatched vulnerabilities to compromise the confidentiality, integrity, or availability of data, or to access other systems.
  • Code vulnerability: Code vulnerability findings identify lines in your AWS Lambda code that bad actors could exploit. Code vulnerabilities include injection flaws, data leaks, weak cryptography, or missing encryption in your code. It identifies policy violations and vulnerabilities based on internal detectors developed in collaboration with CodeGuru Security. For a list of possible detections, see the Amazon Q Detector Library.
  • Network reachability: Network reachability findings show whether your ports are reachable from the internet through an internet gateway (including instances behind Application Load Balancers or Classic Load Balancers), a VPC peering connection, or a VPN through a virtual gateway. These findings highlight network configurations that may be overly permissive, such as mismanaged security groups, NACLs or internet gateways, or that might allow for potentially malicious access. It can help identify open SSH ports on your instance security groups.

AWS WAF

Complementing your network security controls and vulnerability management, AWS WAF provides an additional layer of defense by filtering malicious web traffic that could lead to credential exposure.

AWS WAF offers several managed rule groups to protect against unauthorized access and common vulnerabilities:

  • AWS WAF Fraud Control account creation fraud prevention (ACFP) rule group: ACFP uses request tokens to gather information about the client browser and about the level of human interactivity in the creation of the account creation request. The rule group detects and manages bulk account creation attempts by aggregating requests by IP address and client session and aggregating by the provided account information such as the physical address and phone number. Additionally, the rule group detects and blocks the creation of new accounts using credentials that have been compromised, which helps protect the security posture of your application and of your new users.
  • AWS WAF Fraud Control account takeover prevention (ATP) rule group: To help prevent account takeovers that might lead to fraudulent activity, ATP gives you visibility and control over anomalous sign-in attempts and sign-in attempts that use stolen credentials. For Amazon CloudFront distributions, in addition to inspecting incoming sign-in requests, the ATP rule group inspects your application’s responses to sign-in attempts to track success and failure rates. ATP checks email and password combinations against its stolen credential database, which is updated regularly as new leaked credentials are found on the dark web.

Operational best practices

To complement these protective layers and maintain ongoing security posture, implement automated credential management through Secrets Manager to help facilitate proper rotation and lifecycle management of access keys throughout your environment. This automation reduces human error, helps facilitate timely credential updates and limits the exposure window if credentials are compromised.

It’s recommended to rotate keys at least every 90 days. Secrets Manager helps by automating the process of rotating secrets on a schedule, helping to make sure that credentials are regularly updated without manual intervention. It also centralizes the storage of secrets, reducing the likelihood of sharing access keys among multiple users. With Secrets Manager, you can configure automatic key rotation using a Lambda integration.

There is also an existing solution that can be deployed to implement automatic access key rotation at scale. This pattern helps you automatically rotate IAM access keys by using AWS CloudFormation templates, which are provided in the GitHub IAM key rotation repository.

If you’re unable to implement automatic rotation and need a quicker way to identify access keys that need to be rotated, AWS Trusted Advisor has a security check for IAM access key rotation that checks for active IAM access keys that haven’t been rotated in the last 90 days. You can use the security check to drill down on which access keys in your environment need to be rotated if you need to perform manual rotation.

Detect anomalous IAM activity

Finally, while proactive measures to secure your IAM infrastructure are crucial, it’s equally important to have robust detection and alerting mechanisms in place. No matter how diligent your efforts, there is still a possibility of unforeseen threats or unauthorized activities. That’s why a comprehensive defense-in-depth strategy should include the ability to quickly identify and respond to anomalous IAM-related events. Amazon GuardDuty combines machine learning and integrated threat intelligence to help protect AWS accounts, workloads, and data from threats.

GuardDuty Extended Threat Detection automatically correlates multiple events across different data sources to identify potential threats within AWS environments. When Extended Threat Detection detects suspicious sequences of activities, it generates comprehensive attack sequence findings. The system analyzes individual API activities as weak signals, which might not indicate risks independently, but when observed together in specific patterns can reveal potential security issues.

This capability is enabled by default when GuardDuty is activated in an AWS account, helping provide protection without additional configuration.

The specific attack sequence finding related to compromised credentials is AttackSequence:IAM/CompromisedCredentials which is marked as Critical severity. This finding informs you that GuardDuty detected a sequence of suspicious actions made by using AWS credentials that impacts one or more resources in your environment. Multiple suspicious and anomalous threat behaviors were observed by the same credentials, resulting in higher confidence that the credentials are being misused.

Conclusion

The security best practices outlined in this post provide a comprehensive, multi-layered approach to mitigate the risks associated with long-term credentials. By implementing proactive code scanning, automated key rotation, network-level controls, data perimeter restrictions, and threat detection, you can significantly reduce the attack surface and better protect your organization’s AWS resources until a full migration to temporary credentials is feasible.

While the recommendations provided in this post represent an ample set of controls to put organizations in a good security posture, there might be additional security measures that can be taken depending on the specific needs and risk profile of each environment. The key is to adopt a holistic, layered approach to credential management and protection. By doing so, you can bridge the gap until a complete transition to temporary credentials becomes possible.

Implementing these security measures can help reduce risks, but long-term credentials inherently carry security risks. Even with strict best practices and comprehensive security controls, the possibility of credential compromise cannot be removed completely. You should consider evaluating your organization’s security posture and prioritizing temporary credentials through IAM roles and federation whenever possible. If you have questions or need help, AWS is here to support you.

Jennifer Paz
Jennifer Paz

Jennifer is a Security Engineer with over a decade of experience, currently serving on the AWS Customer Incident Response Team (CIRT). Jennifer enjoys helping customers tackle security challenges and implementing complex solutions to help enhance their security posture. When not at work, Jennifer is an avid runner, pickleball enthusiast, traveler, and foodie, always on the hunt for new culinary adventures.
Samantha Tavares
Samantha Tavares

Samantha is an Incident Responder on the AWS Customer Incident Response Team. She’s passionate about helping customers protect their cloud environments. When she’s not diving into security challenges, she’s sweating at CrossFit, or planning her next travel adventure.

Accelerate investigations with AWS Security Incident Response AI-powered capabilities

Post Syndicated from Daniel Begimher original https://aws.amazon.com/blogs/security/accelerate-investigations-with-aws-security-incident-response-ai-powered-capabilities/

If you’ve ever spent hours manually digging through AWS CloudTrail logs, checking AWS Identity and Access Management (IAM) permissions, and piecing together the timeline of a security event, you understand the time investment required for incident investigation. Today, we’re excited to announce the addition of AI-powered investigation capabilities to AWS Security Incident Response that automate this evidence gathering and analysis work.

AWS Security Incident Response helps you prepare for, respond to, and recover from security events faster and more effectively. The service combines automated security finding monitoring and triage, containment, and now AI-powered investigation capabilities with 24/7 direct access to the AWS Customer Incident Response Team (CIRT).

While investigating a suspicious API call or unusual network activity, scoping and validation require querying multiple data sources, correlating timestamps, identifying related events, and building a complete picture of what happened. Security operations center (SOC) analysts devote a significant amount of time to each investigation, with roughly half of that effort spent manually gathering and piecing together evidence from various tools and complex logs. This manual effort can delay your analysis and response.

AWS is introducing an investigative agent to Security Incident Response, changing this paradigm and adding layers of efficiency. The investigative agent helps you reduce the time required to validate and respond to potential security events. When a case for a security concern is created, either by you or proactively by Security Incident Response, the investigative agent asks clarifying questions to make sure it understands the full context of the potential security event. It then automatically gathers evidence from CloudTrail events, IAM configurations, and Amazon Elastic Compute Cloud (Amazon EC2) instance details and even analyzes cost usage patterns. Within minutes, it correlates the evidence, identifies patterns, and presents you with a clear summary.

How it works in practice

Before diving into an example, let’s paint a clear picture of where the investigative agent lives, how it’s accessed, and its purpose and function. The investigative agent is built directly into Security Incident Response and is automatically available when you create a case. Its purpose is to act as your first responder—gathering evidence, correlating data across AWS services, and building a comprehensive timeline of events so you can quickly move from detection to recovery.

For example: you discover that AWS credentials for an IAM user in your account were exposed in a public GitHub repository. You need to understand what actions were taken with those credentials and properly scope the potential security event, including lateral movement and reconnaissance operations. You need to identify persistence mechanisms that might have been created and determine the appropriate containment steps. To get started, you create a case in the Security Incident Response console and describe the situation.

Here’s where the agent’s approach differs from traditional automation: it asks clarifying questions first. When were the credentials first exposed? What’s the IAM user name? Have you already rotated the credentials? Which AWS account is affected?

This interactive step gathers the appropriate details and metadata before it starts gathering evidence. Specifically, you’re not stuck with generic results—the investigation is tailored to your specific concern.

After the agent has what it needs, it investigates. It looks up CloudTrail events to see what API calls were made using the compromised credentials, pulls IAM user and role details to check what permissions were granted, identifies new IAM users or roles that were created, checks EC2 instance information if compute resources were launched, and analyzes cost and usage patterns for unusual resource consumption. Instead of you querying each AWS service, the agent orchestrates this automatically.

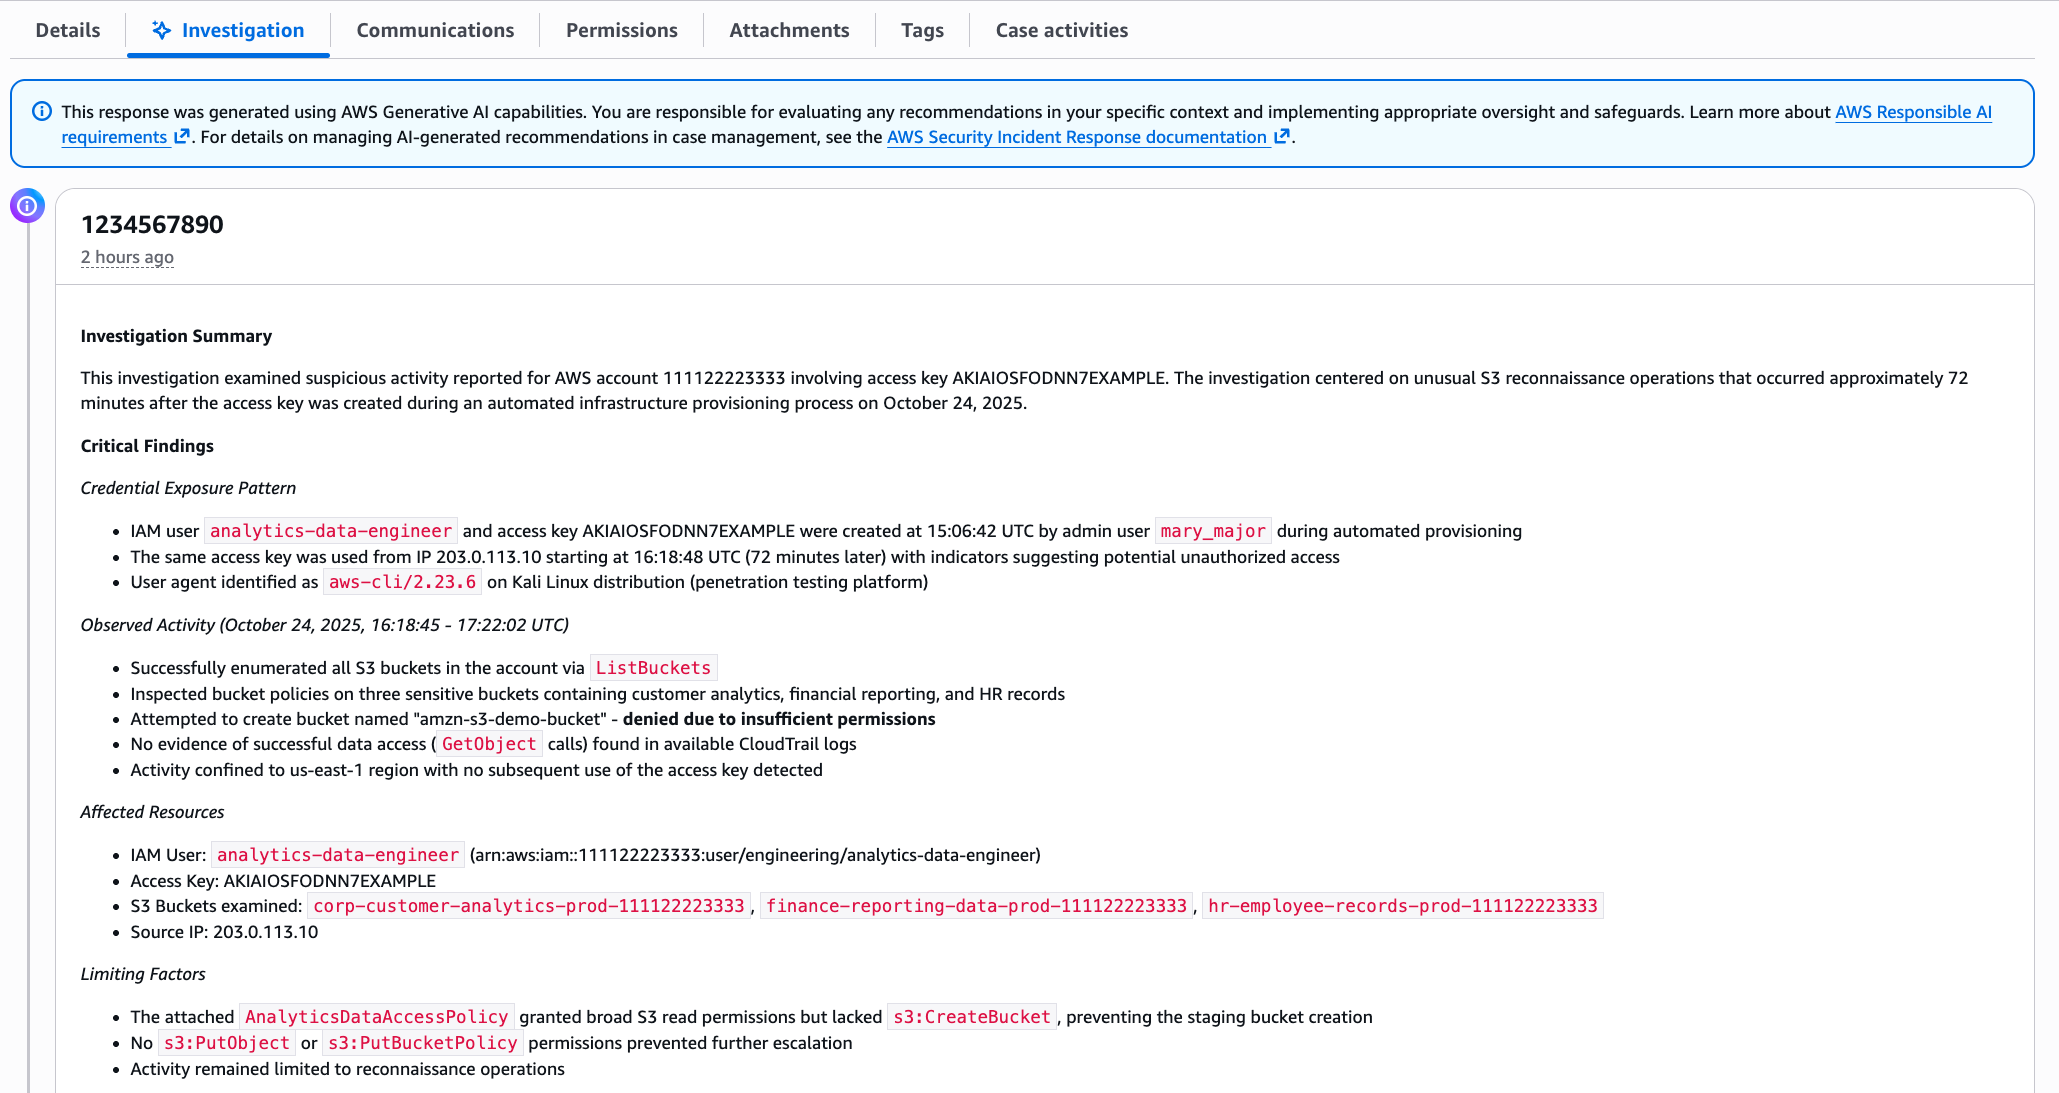
Within minutes, you get a summary, as shown in the following figure. The investigation summary includes a high-level summary and critical findings, which include the credential exposure pattern, observed activity and the timeframe, affected resources, and limiting factors.

This response was generated using AWS Generative AI capabilities. You are responsible for evaluating any recommendations in your specific context and implementing appropriate oversight and safeguards. Learn more about AWS Responsible AI requirements.

Note: The preceding example is representative output. Exact formatting will vary depending on findings.

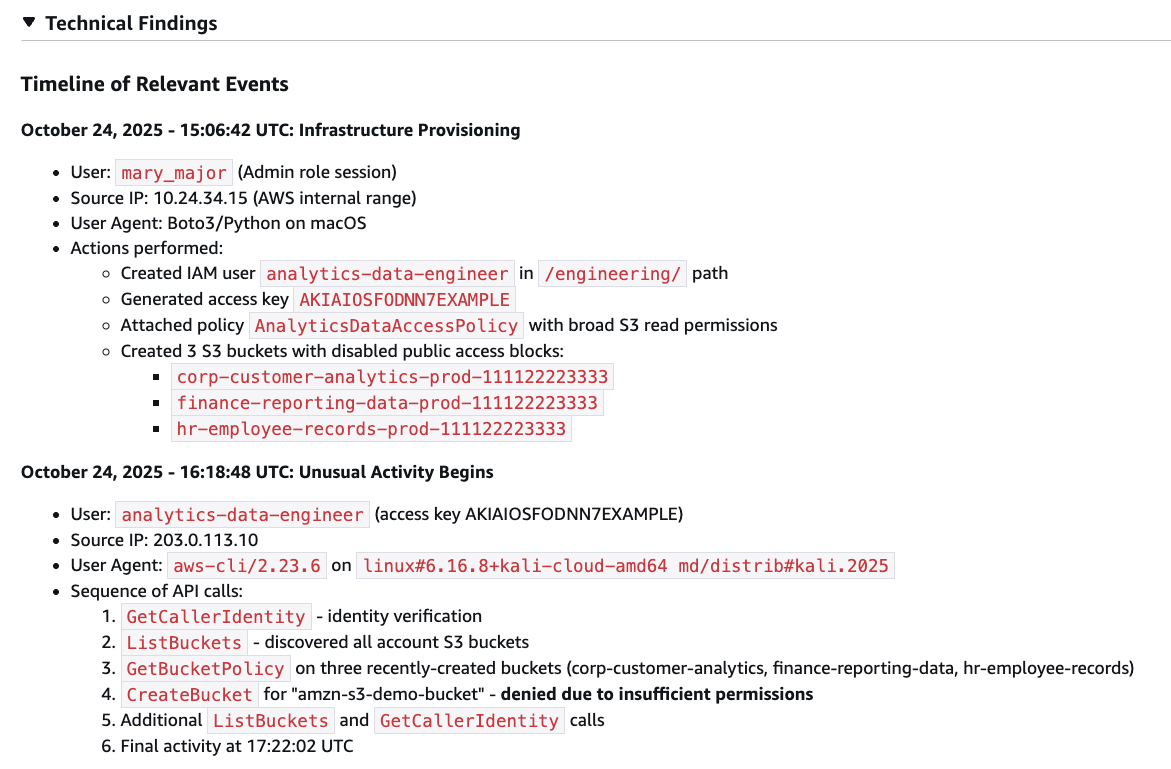
The investigation summary includes various tabs for detailed information, such as technical findings with an events timeline, as shown in the following figure:

Figure 2 – Security event timeline

Figure 2 – Security event timeline

When seconds count, this transparency is paramount to a quick, high-fidelity, and accurate response—especially if you need to escalate to the AWS CIRT, a dedicated group of AWS security experts, or explain your findings to leadership, creating a single lens for stakeholders to view the incident.

When the investigation is complete, you have a high-resolution picture of what happened and can make informed decisions about containment, eradication, and recovery. For the preceding exposed credentials scenario, you might need to:

  • Delete the compromised access keys
  • Remove the newly created IAM role
  • Terminate the unauthorized EC2 instances
  • Review and revert associated IAM policy changes
  • Check for additional access keys created for other users.

When you engage with the CIRT, they can provide additional guidance on containment strategies based on the evidence the agent gathered.

What this means for your security operations

The leaked credentials scenario shows what the agent can do for a single incident. But the bigger impact is on how you operate day-to-day:

  • You spend less time on evidence collection. The investigative agent automates the most time-consuming part of investigations—gathering and correlating evidence from multiple sources. Instead of spending an hour on manual log analysis, you can spend most of that time on making containment decisions and preventing recurrence.
  • You can investigate in plain language. The investigative agent uses natural language processing (NLP), which you can use to describe what you’re investigating in plain language, such as unusual API calls from IP address X or data access from terminated employee’s credentials, and the agent translates that into the technical queries needed. You don’t need to be an expert in AWS log formats or know the exact syntax for querying CloudTrail.
  • You get a foundation for high-fidelity and accurate investigations. The investigative agent handles the initial investigation—gathering evidence, identifying patterns, and providing a comprehensive summary. If your case requires deeper analysis or you need guidance on complex scenarios, you can engage with the AWS CIRT, who can immediately build on the work the agent has already done, speeding up their response time. They see the same evidence and timeline, so they can focus on advanced threat analysis and containment strategies rather than starting from scratch.

Getting started

If you already have Security Incident Response enabled, the AI-powered investigation capabilities are available now—no additional configuration needed. Create your next security case and the agent will start working automatically.

If you’re new to Security Incident Response, here’s how to set it up:

  1. Enable Security Incident Response through your AWS Organizations management account. This takes a few minutes through the AWS Management Console and provides coverage across your accounts.
  2. Create a case. Describe what you’re investigating; you can do this through the Security Incident Response console or an API, or set up automatic case creation from Amazon GuardDuty or AWS Security Hub alerts.
  3. Review the analysis. The agent presents its findings through the Security Incident Response console, or you can access them through your existing ticketing systems such as Jira or ServiceNow.

The investigative agent uses the AWS Support service-linked role to gather information from your AWS resources. This role is automatically created when you set up your AWS account and provides the necessary access for Support tools to query CloudTrail events, IAM configurations, EC2 details, and cost data. Actions taken by the agent are logged in CloudTrail for full auditability.

The investigative agent is included at no additional cost with Security Incident Response, which now offers metered pricing with a free tier covering your first 10,000 findings ingested per month. Beyond that, findings are billed at rates that decrease with volume. With this consumption-based approach, you can scale your security incident response capabilities as your needs grow.

How it fits with existing tools

Security Incident Response cases can be created by customers or proactively by the service. The investigative agent is automatically triggered when a new case is created, and cases can be managed through the console, API, or Amazon EventBridge integrations.

You can use EventBridge to build automated workflows that route security events from GuardDuty, Security Hub, and Security Incident Response itself to create cases and initiate response plans, enabling end-to-end detection-to-investigation pipelines. Before the investigative agent begins its work, the service’s auto-triage system monitors and filters security findings from GuardDuty and third-party security tools through Security Hub. It uses customer-specific information, such as known IP addresses and IAM entities, to filter findings based on expected behavior, reducing alert volume while escalating alerts that require immediate attention. This means the investigative agent focuses on alerts that actually need investigation.

Conclusion

In this post, I showed you how the new investigative agent in AWS Security Incident Response automates evidence gathering and analysis, reducing the time required to investigate security events from hours to minutes. The agent asks clarifying questions to understand your specific concern, automatically queries multiple AWS data sources, correlates evidence, and presents you with a comprehensive timeline and summary while maintaining full transparency and auditability.

With the addition of the investigative agent, Security Incident Response customers now get the speed and efficiency of AI-powered automation, backed by the expertise and oversight of AWS security experts when needed.

The AI-powered investigation capabilities are available today in all commercial AWS Regions where Security Incident Response operates. To learn more about pricing and features, or to get started, visit the AWS Security Incident Response product page.

If you have feedback about this post, submit comments in the Comments section below.

Daniel Begimher

Daniel Begimher

Daniel is a Senior Security Engineer in Global Services Security, specializing in cloud security, application security, and incident response. He co-leads the Application Security focus area within the AWS Security and Compliance Technical Field Community, holds all AWS certifications, and authored Automated Security Helper (ASH), an open source code scanning tool.

The Agentic AI Security Scoping Matrix: A framework for securing autonomous AI systems

Post Syndicated from Aaron Brown original https://aws.amazon.com/blogs/security/the-agentic-ai-security-scoping-matrix-a-framework-for-securing-autonomous-ai-systems/

As generative AI became mainstream, Amazon Web Services (AWS) launched the Generative AI Security Scoping Matrix to help organizations understand and address the unique security challenges of foundation model (FM)-based applications. This framework has been adopted not only by AWS customers across the globe, but also widely referenced by organizations such as OWASP, CoSAI, and other industry standards bodies, partners, systems integrators (SIs), analysts, auditors, and more. Now, as long-running, function-calling agentic AI systems emerge with capabilities for autonomous decision-making, we’re creating an additional framework to address an entirely new set of security challenges.

Agentic AI systems can autonomously execute multi-step tasks, make decisions, and interact with infrastructure and data. This is a paradigm shift, and organizations must adapt to it. Unlike traditional FMs that operate in stateless request-response patterns, agentic AI systems introduce autonomous capabilities, persistent memory, tool orchestration, identity and agency challenges, and external system integration, expanding the risks that organizations must address.

Working with customers deploying these systems, we’ve observed that traditional AI security frameworks don’t always extend into the agentic space. The autonomous nature of agentic systems requires fundamentally different security approaches. To address this gap, we’ve developed the Agentic AI Security Scoping Matrix, a mental model and framework that categorizes four distinct agentic architectures based on connectivity and autonomy levels, mapping critical security controls across each.

Understanding the agentic paradigm shift

FM-powered applications operate in a now well-understood, predictable pattern even though the responses that an FM produces are non-deterministic and stateless. These applications, in their most basic form receive a prompt or instruction, generate a response, then terminate the session. Security and safety controls focus on basic measures such as input validation, output filtering, and content moderation guardrails, while governance focuses on the overall risk profiles and the resilience of models. This model works because security failures have limited scope: a compromised interaction affects only that specific request and response, without persisting or propagating to other systems or users.

Agentic AI systems fundamentally change this security model through several key capabilities:

Autonomous execution and agency: Agents initiate actions based on goals and environmental triggers that might, or might not, require human prompts or approval. This creates risks of unauthorized actions, runaway processes, and decisions that exceed intended boundaries when agents misinterpret objectives or operate on compromised instructions.

When AI agents are given instructions or permissions to act based on the data, parameters, instructions, and responses given to them, the boundaries of independence or autonomy they are permitted to act within are important to define. In discussing agentic AI systems, it’s important to clarify the distinction between agency and autonomy, because these related but different concepts inform our security approach.

Agency refers to the scope of actions an AI system is permitted and enabled to take within the operating environment, and how much a human bounds an agent’s actions or capabilities. This includes what systems it can interact with, what operations it can perform, and what resources it can modify. Agency is fundamentally about capabilities and permissions—what the system is allowed to do within its operational environment. For example, an AI agent with no agency would be guided by human-defined workflow, process, tools, or orchestration compared to an AI agent with full agency that can self-determine how to accomplish a human-defined goal.

Autonomy, in contrast, refers to the degree of independent decision-making and action the system can take without human intervention. This includes when it operates, how it chooses between available actions, and whether it requires human approval for execution. Autonomy is about independence in decision-making and execution—how freely the system can act within its granted agency. For example, an AI agent might have high agency (able to perform many actions) but low autonomy (requiring human approval for each action), or vice versa.

Understanding this distinction is crucial for implementing appropriate security controls. Agency requires boundaries and permission systems, while autonomy requires oversight mechanisms and behavioral controls. Both dimensions must be carefully managed to create secure agentic AI systems.

It’s important to determine how much agency and autonomy you want to permit and grant your AI agents to act within. After you have determined the appropriate level that any given agent should operate within, you can then evaluate the appropriate security controls to put in place to restrict the agency to a permissible risk tolerance for your agentic-based application and your organization.

Persistent memory: Agents often benefit from maintaining context and learned behaviors across sessions, building knowledge bases that inform future decisions in the form of short- and long-term memory. This data persistence introduces additional data protection requirements and can add new risk vectors such as memory poisoning attacks where adversaries inject false information that corrupts decision-making across multiple interactions and users.

Tool orchestration: Agents directly integrate via functions with connections to databases, APIs, services, and potentially other agents or orchestration components to execute complex tasks autonomously depending on the tool abstraction level. This expanded attack surface creates risks of cascading compromises where a single agent breach can propagate through connected systems, multi-agent workflows, and downstream services and data stores.

External connectivity: Agents operate across network boundaries, accessing internet resources, third-party APIs, and enterprise systems. Like traditional non-agentic systems, expanded connectivity can help unlock new business value, but this access should be designed with security controls that limit risks such as data exfiltration, lateral movement, and external manipulation. Threat modeling your agentic AI applications should be a high priority and can help directly align security controls that assist your implementation of zero-trust principles into your strategy.

Self-directed behavior: Advanced agents can initiate activities based on environmental monitoring, scheduling, or learned patterns without human instantiation or review, depending on configuration. This self-direction introduces risks of uncontrolled operations, explainability, and auditability, and makes it difficult to maintain predictable security boundaries.

These capabilities transform security from a boundary problem to a continuous monitoring and control challenge. A compromised agent doesn’t just leak information—it could autonomously execute unauthorized transactions, modify critical infrastructure, or operate maliciously for extended periods without detection.

The Agentic AI Security Scoping Matrix

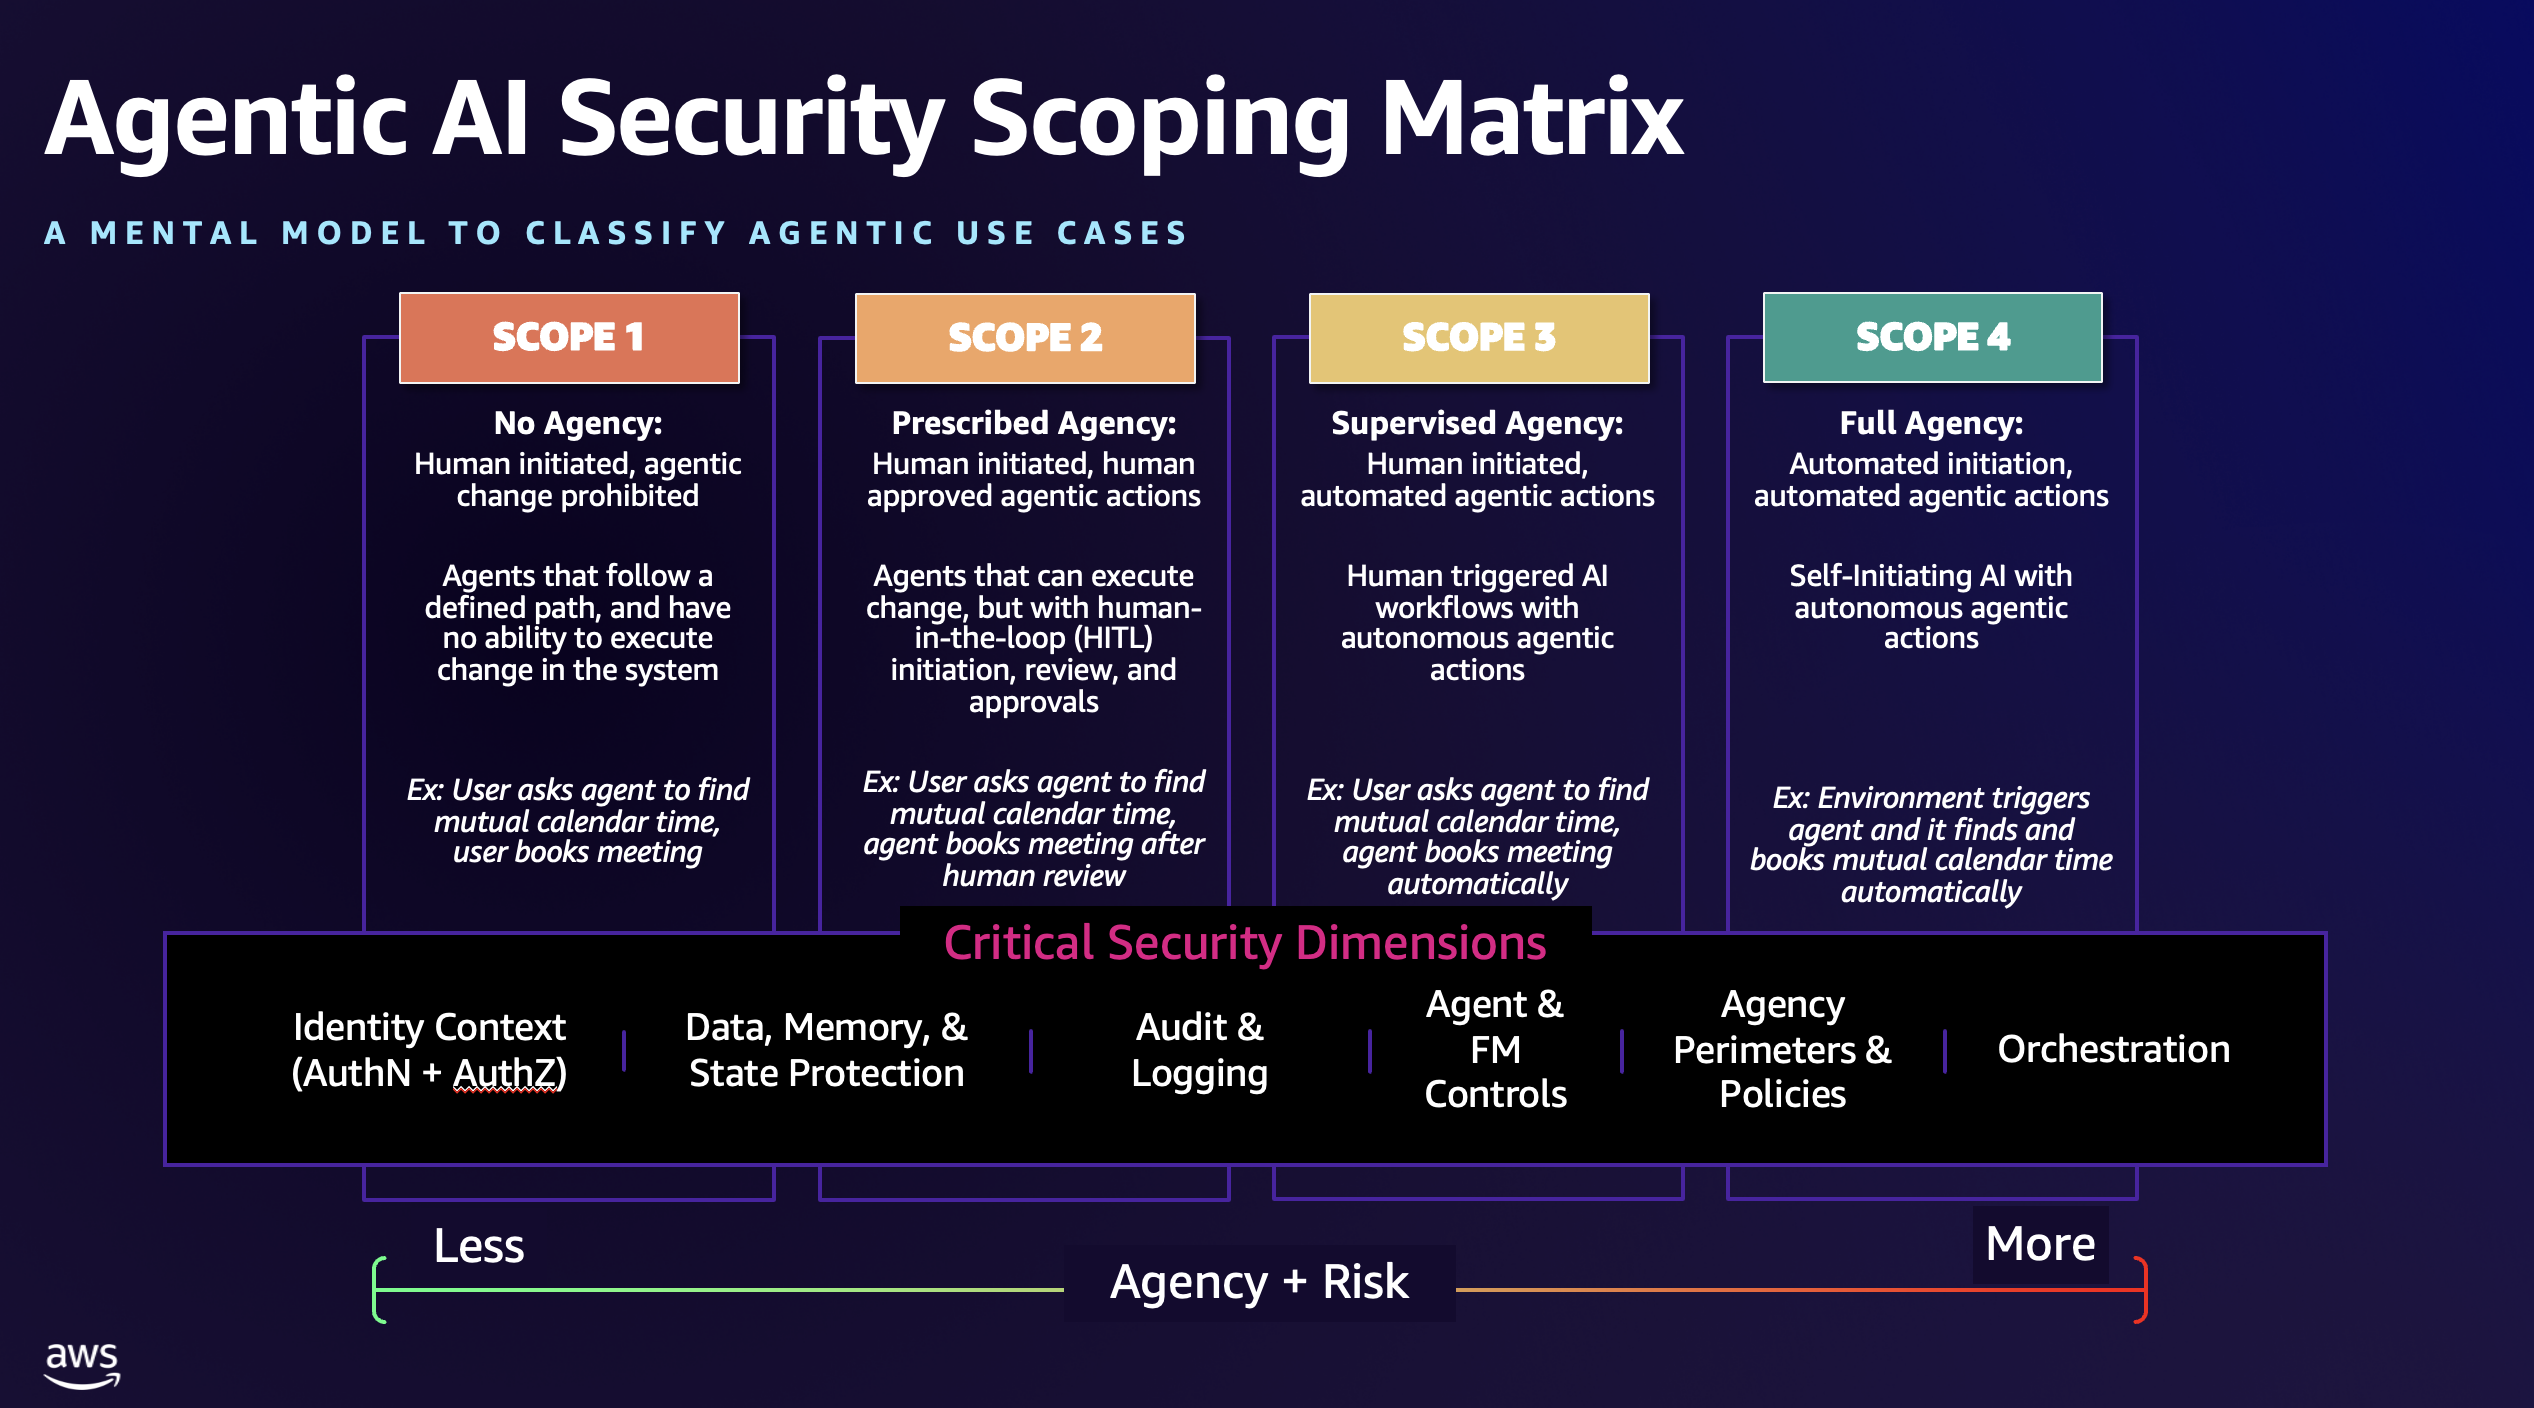
Working with customers and the community, we’ve identified four architectural scopes that represent the evolution of agentic AI systems based on two critical dimensions: level of human oversight compared with autonomy and the level of agency the AI system is permitted to act within. Each scope introduces new capabilities—and corresponding security requirements—that organizations must prioritize when addressing agentic AI risk. Figure 1 shows the Agentic AI Security Scoping Matrix.

Figure 1 - The Agentic AI Security Scoping Matrix

Figure 1 – The Agentic AI Security Scoping Matrix

Scope 1: No agency

In this most basic scope, systems operate with human-initiated processes and no autonomous or even human-approved change capabilities through the agent itself. The agents are, essentially, read-only. These systems follow predefined execution paths and operate under strict human-triggered workflows, which are usually predefined and follow discrete steps, but could be augmented with non-deterministic outputs from an FM. Security focuses primarily on process integrity and boundary enforcement, helping operations remain within predetermined limits and agents are highly controlled and prohibited from change execution and unbounded actions.

Key characteristics:

  • Agents can’t directly execute change in the environment
  • Fixed step-by-step execution following predetermined paths
  • Generative AI components process data within individual workflow nodes
  • Conditional branching only where explicitly designed into the workflow
  • No dynamic planning or autonomous goal-seeking behavior
  • State persistence limited to workflow execution context
  • Tool access restricted to specific predefined workflow steps

Security focus: Protecting data integrity within the environment and restricting agents to not exceed their boundaries, especially limits around environment and data modification. Primary concerns include securing state transitions between steps, validating data passed between workflow nodes, and preventing AI components from modifying the orchestration logic or escaping their designated boundaries within the workflow.

Example: We will use a very simplistic example, across all four scopes, of a use case for an agent that is designed to help you create calendar invites. Let’s say you need to book a meeting with another colleague. In Scope 1, you might have an agent that you instantiate through a workflow or prompt to look at your calendar and your colleague’s calendar for available meeting times. In this case, you initiate the request, and the agent executes a contextual search using a Model Context Protocol (MCP) server connected to your enterprise calendaring application. The agent is only allowed to look at available times, analyze the best times to meet, and provide a response back, which a human can then use to manually set up a meeting. In this example, the human defines specific workflows and orchestrations (no agency) and reviews and approves the actions taken (no autonomous change).

Scope 2: Prescribed agency

Moving up in agency and risk, Scope 2 systems also are instantiated by a human, but now have the potential to perform actions—limited agency—that could change the environment. However, all actions taken by an agent require explicit human approval for all actions of consequence—commonly referred to as human in the loop or HITL. These systems can gather information, analyze data, and prepare recommendations, but cannot execute actions that modify external systems or access sensitive resources without human authorization. Agents can also request human input to clarify ambiguities, provide missing context, or optimize their approach before presenting recommendations.

Key characteristics:

  • Agents can execute change in the environment with human review and approval
  • Real-time human oversight with approval workflows
  • Bidirectional human interaction—agents can query humans for context
  • Limited autonomous actions restricted to read-only operations (such as, querying data, running analysis jobs, and so on)
  • Agent-initiated requests for clarification or additional information
  • Audit trails of all human approval decisions and context exchanges

Security focus: Implementing robust approval workflows and preventing agents from bypassing human authorization controls. Key concerns include preventing privilege escalation, enforcing appropriate identity contexts, securing the approval process itself, validating human-provided context to prevent injection attacks, and maintaining visibility into all agent recommendations and their rationale.

Example: In our calendaring example, a Scope 2 agentic system is instantiated by a human. The agent then looks up the stakeholders’ calendar availability, does its analysis, returns a recommendation for a meeting time to the user, and asks the user if they want the agent to send the invitation out on their behalf. The user looks at the response and recommendation of the agent, validates that it meets their requirements, and then acknowledges and approves the agent’s request to modify the calendars and send the invitation. In this example, the human orchestrates a structured workflow, but the agent now can instantiate human reviewed change through bounded actions (limited agency and limited autonomy).

Scope 3: Supervised agency

In Scope 3, we expand the agency to allow for a greater sense of agentic autonomy—high agency—in execution. These are AI systems that execute complex autonomous tasks that are initiated by humans (or at least from an upstream human-managed workflow), with the ability to make decisions and take actions to connected systems without further approval or HITL mechanisms. Humans define the objectives and trigger execution, but agents operate independently to achieve goals through dynamic planning and tool usage. During execution, agents can request human guidance to optimize trajectory or handle edge cases, though they can continue operating without it.

Key characteristics:

  • Agents can execute change in the environment, with no (or optional) human interaction or review
  • Human-triggered execution with autonomous task completion
  • Dynamic planning and decision-making during execution
  • Optional human intervention points for trajectory optimization
  • Human ability to adjust parameters or provide context mid-execution
  • Direct access to external APIs and systems for task completion
  • Persistent memory across extended execution sessions
  • Autonomous tool selection and orchestration within defined boundaries

Security focus: Implementing comprehensive monitoring of agent actions during autonomous execution phases and establishing clear agency boundaries for agent operations—the bounds you’re willing to let the agents operate within, and actions that would be out of bounds and must be prevented. Critical concerns include securing the human intervention channel to prevent unauthorized modifications, preventing scope creep during task execution, implementing trusted identity propagation constructs, monitoring for behavioral anomalies, and validating that agents remain aligned with original human intent throughout extended operations even when trajectory adjustments are made.

Example: In our calendaring example, a Scope 3 agentic system can still be instantiated by a human. The agent then looks up the stakeholders’ calendar availability, does its analysis, and returns a recommendation for a meeting time to the user; however, it’s within the agent’s bounds to act upon its own recommendation on behalf of the user to automatically book the best available slot. The user is not prompted or expected to give the agent permission to do so prior to its actions. The result is that all stakeholders have a calendar entry added to their calendar in the context of the calling human user. In this example, the human defines an outcome but with more freedom for the agent to determine how to achieve that goal, and the agent now can take autonomous action without human review (high agency and high autonomy).

Scope 4: Full agency

Scope 4 includes fully autonomous AI systems that can initiate their own activities based on environmental monitoring, learned patterns, or predefined conditions, and execute complex tasks without human intervention. These systems represent the highest level of AI agency, operating continuously and making independent decisions about when and how to act. It’s key to note that AI systems within Scope 4 could have full agency when executing within their designed bounds; therefore, it’s critical that humans maintain supervisory oversight with the ability to provide strategic guidance, course corrections, or interventions when needed. Continuous compliance, auditing, and full-lifecycle management mechanisms, both human and automated reviews, which could also be aided by AI, are critical to successfully securing and governing Scope 4 agentic AI systems while limiting risk.

Key characteristics:

  • Self-directed activity initiation based on environmental triggers
  • Continuous operation with minimal human oversight or HITL processes during execution
  • Human ability to inject strategic guidance without disrupting operations
  • High to full degrees of autonomy in goal setting, planning, and execution
  • Dynamic interaction with multiple external systems and agents
  • Capability for recursive self-improvement and capability expansion

Security focus: Implementing advanced guardrails for behavioral monitoring, anomaly detection, scope-based tool access controls, and fail-safe mechanisms to prevent runaway operations. Primary concerns include maintaining alignment with organizational objectives, securing human intervention channels against adversarial manipulation, preventing unauthorized capability expansion, preventing human oversight mechanisms from being disabled by the agent, and enabling graceful degradation when agents encounter unexpected situations.

Example: Let’s look at how we might deploy our AI calendaring example in Scope 4. Let’s say you have implemented a generative AI meeting summarizer. This agent is automatically enabled when you host a web conference. At the conclusion of the meeting, the calendaring agent sees a new meeting occurred from the meeting summarizer agent. It looks at the action items that were summarized and determines that six people agreed to a whiteboard session on Friday. The calendaring agent might either have a statically defined API configuration or leverage dynamic discovery on MCP servers to help with calendaring. It then finds availability for the six identified resources and books the best available slot. It then uses the appropriate identity context of the user who is asking for the meeting to book the meeting autonomously. At no point does a user directly instantiate the request for calendaring; it is fully automated and driven off environment changes that the agent is instructed to look for (full agency and full autonomy).

Scope comparison across the scopes

In the context of the security scoping matrix, let’s compare how autonomy and agency characteristics shift depending on the scope:

Table 1 – Scope impacts on agency and autonomy levels

Critical security dimensions

Scope

Agency level

Agency characteristics

Autonomy level

Autonomy characteristics

Scope 1: No agency

None

  • Read-only operations
  • Fixed workflow paths

None

  • Human-initiated only
  • Predefined execution steps

Scope 2: Prescribed agency

Limited

  • Can modify systems
  • Access to multiple tools

Limited

  • Requires human approval for actions
  • HITL for all changes

Scope 3: Supervised agency

High

  • Can modify multiple systems
  • Dynamic tool selection

High

  • Autonomous execution after human initiation
  • Optional human guidance

Scope 4: Full agency

Full

  • Comprehensive system access
  • Multi-system orchestration
  • Self-adaptive

Full

  • Self-initiated actions
  • Continuous autonomous operation
  • Strategic human oversight

Each architectural scope requires specific security controls and considerations across six critical dimensions. Table 2 illustrates how security requirements escalate with increasing agency and autonomy:

Security dimension

Scope 1: No agency

Scope 2: Prescribed agency

Scope 3: Supervised agency

Scope 4: Full agency

Identity context (authN and authZ)

  • User authentication
  • Service authentication
  • Limited system permissions (read-only)
  • Limited system access (only necessary, known systems needed for the workflow)
  • User authentication
  • Service authentication
  • Human identity verification for approvals
  • User authentication
  • Service authentication
  • Agent authentication
  • Identity delegation for autonomous actions
  • Dynamic identity lifecycle
  • Federated authentication
  • Continuous identity verification
  • Agent identity attestation

Data, memory, and state protection

  • Local resource permissions
  • File system access controls
  • Role-based access control
  • Human approval workflows
  • Read-mostly permissions for agents
  • Context-aware authorization
  • Just-in-time privilege elevation
  • Dynamic permission boundaries
  • Behavioral authorization
  • Adaptive access controls
  • Continuous authorization validation

Audit and logging

  • Local activity logs
  • Change tracking
  • Integrity monitoring
  • Policy enforcement
  • Human decision audit trails
  • Agent recommendation logging
  • Approval process tracking
  • Comprehensive action logging
  • Reasoning chain capture
  • Extended session tracking
  • Continuous behavioral logging
  • Pattern analysis
  • Predictive monitoring
  • Automated incident correlation

Agent and FM controls

  • Process isolation
  • Input/output validations
  • Guardrails
  • Approval gateway enforcement
  • Extended session monitoring
  • Container isolation
  • Long-running process management
  • Tool invocation sandboxing
  • Behavioral analysis
  • Anomaly detection
  • Automated containment
  • Self-healing security

Agency perimeters and policies

  • Fixed execution boundaries
  • Predefined action limits
  • Static resource quotas
  • Hard-coded constraints
  • Approval-based boundary modification
  • Human-validated constraint changes
  • Time-bound elevated access
  • Multi-step validation
  • Dynamic boundary adjustment
  • Runtime constraint evaluation
  • Resource scaling limits
  • Automated safety checks
  • Self-adjusting boundaries
  • Context-aware constraints
  • Cross-system resource management
  • Autonomous limit adaptation

Orchestration

  • Simple workflow orchestration
  • Fixed execution paths
  • Single or limited system integration points
  • Multi-step workflow orchestration
  • Approval-gated tool access
  • Human-validated tool chains
  • Dynamic tool orchestration
  • Parallel execution paths
  • Cross-system integration
  • Autonomous multi-agent orchestration
  • Cross-session learning
  • Dynamic service discovery

Table 2 — Critical security dimensions per scope

Security implementation by scope

Now that we’ve outlined each of the scopes and the associated levels of agency and autonomy, let’s discuss some primary security challenges per scope and key considerations that should be taken to address the associated risks.

Scope 1: No agency
Primary security challenges: Protecting workflow integrity, preventing prompt injection from breaking predetermined flows, and maintaining isolation between workflow executions.

Implementation considerations:

  • Comprehensive monitoring with anomaly detection
  • Strict data validation and integrity checking
  • Input validation at each workflow step boundary
  • Immutable workflow definitions with version control
  • State encryption and validation between workflow nodes
  • Monitoring for attempts to escape workflow boundaries
  • Segregation between different workflow executions
  • Fixed timeout and resource limits per workflow step
  • Audit trails showing actual compared to expected execution paths

Scope 2: Prescribed agency
Primary security challenges: Securing approval workflows, preventing human authorization bypass, and maintaining oversight effectiveness.

Implementation considerations:

  • Multi-factor authentication for all human approvers
  • Cryptographically signed approval decisions
  • Securing bidirectional human-agent communication channels
  • Time-bounded approval tokens with automatic expiration
  • Comprehensive logging of all approval interactions
  • Regular training for human approvers on agent capabilities and risks

Scope 3: Supervised agency
Primary security challenges: Maintaining control during autonomous execution, scope management, explainability and auditability, and behavioral monitoring.

Implementation considerations:

  • Clear execution boundaries defined at initiation
  • Real-time monitoring of agent actions during execution
  • Automated kill switches for runaway processes
  • Non-blocking intervention mechanisms
  • Behavioral baselines for normal agent operations
  • Regular validation of agent alignment with original objectives

Scope 4: Full agency
Primary security challenges: Continuous behavioral validation, enforcing agency boundaries, preventing capability drift, and maintaining organizational alignment.

Implementation considerations:

  • Advanced AI safety techniques including reward modeling
  • Continuous monitoring with machine learning-based anomaly detection
  • Automated response systems for behavioral deviations
  • Regular alignment validation through systematic testing
  • Tamper-proof human override mechanisms
  • Failsafe mechanisms that can halt operations when confidence drops

Key architectural patterns

Successful agentic deployments share common patterns that balance autonomy with control.

Progressive autonomy deployment: Start with Scope 1 or 2 implementations and gradually advance through the scopes as organizational confidence and security capabilities mature. This approach minimizes risk while building operational experience. Be cautious and selective when analyzing use cases and bounding controls for Scope 4 implementations and review your ability to address risks at the lower scopes and how risks increase as you move further up the levels.

Layered security architecture: Implement defense-in-depth with security controls at multiple levels—network, application, agent, and data layers—to safeguard that compromise at one level doesn’t lead to complete system failure. Although the combination of these controls is what enables a high security bar, be sure to spend considerable efforts on making sure that identity and authorization concerns are addressed—for both machines and humans. This helps prevent issues such as the confused deputy problem—when a human or service with lesser permissions is able to elevate permissions through agents that might themselves have more entitlements and privileges.

Continuous validation loops: Establish automated systems that continuously verify agent behavior against expected patterns, and that have escalation procedures for when deviations are detected. Auditability and explainability are key requirements to confirm that agents are performing within the bounds intended and to help you determine control effectiveness, adjust parameters, and validate your orchestration workflows.

Human oversight integration: Even in highly autonomous systems, maintain meaningful human oversight through strategic checkpoints, behavioral reporting, and manual override capabilities. It might be reasonable to assume that human oversight reduces when moving from Scope 1 to Scope 4 agency, but the truth is that it simply shifts focus. For example, the human requirement to instantiate, review, and approve certain agentic actions is higher in Scopes 1 and 2 and lower in Scopes 3 and 4; however, the human requirement to audit, assess, validate, and implement more complex security and operational controls is much higher in Scopes 4 and 3 than they are in Scopes 2 and 1.

Graceful degradation: Design systems to automatically reduce autonomy levels when security events are detected, allowing operations to continue safely while human operators investigate. If your agents start to act in ways that go beyond the intended bounds of their design, anomalous behavior is detected, or they begin to perform actions deemed particularly risky or sensitive to your business, then consider having detective controls that will automatically inject tighter restrictions such as requiring more HITL or reducing the actions an agent can take. You might do this as incremental degradation or, you might choose to disable the agent if it’s acting in ways that negatively impact the environment. These agentic safety mechanisms that can implement additional restrictions or even disable an agent should be considered when building or deploying agents.

Conclusion

The Agentic AI Security Scoping Matrix provides a structured mental model and framework for understanding and addressing the security challenges of autonomous agentic AI systems across four distinct scopes. By accurately assessing your current scope and implementing appropriate controls across all six security dimensions, organizations can confidently deploy agentic AI while managing the landscape of associated risks.

The progression from basic and highly constrained agents to fully autonomous and even self-directing agents represents a fundamental shift in how we approach AI security. Each scope requires specific security capabilities, and organizations must build these capabilities systematically to support their agentic ambitions safely.

Next steps

To implement the Agentic AI Security Scoping Matrix in your organization:

  1. Assess your current agentic use cases and maturity against the four scopes to understand your security requirements and associated risks. Integrate it into your procurement and SDLC processes.
  2. Identify capability gaps across the six security dimensions for your target scope.
  3. Develop a progressive deployment strategy that builds security capabilities as you advance through scopes.
  4. Implement continuous monitoring and behavioral analysis appropriate for your scope level.
  5. Establish governance processes for scope progression and security validation.
  6. Train your teams on the unique security challenges of each scope.

You can find additional information on the Agentic AI Security Scoping matrix here, along with additional information on AI security topics. For additional resources on securing AI workloads, see the AI for security and security for AI: Navigating Opportunities and Challenges whitepaper and explore purpose-built platforms designed for the unique challenges of agentic AI.
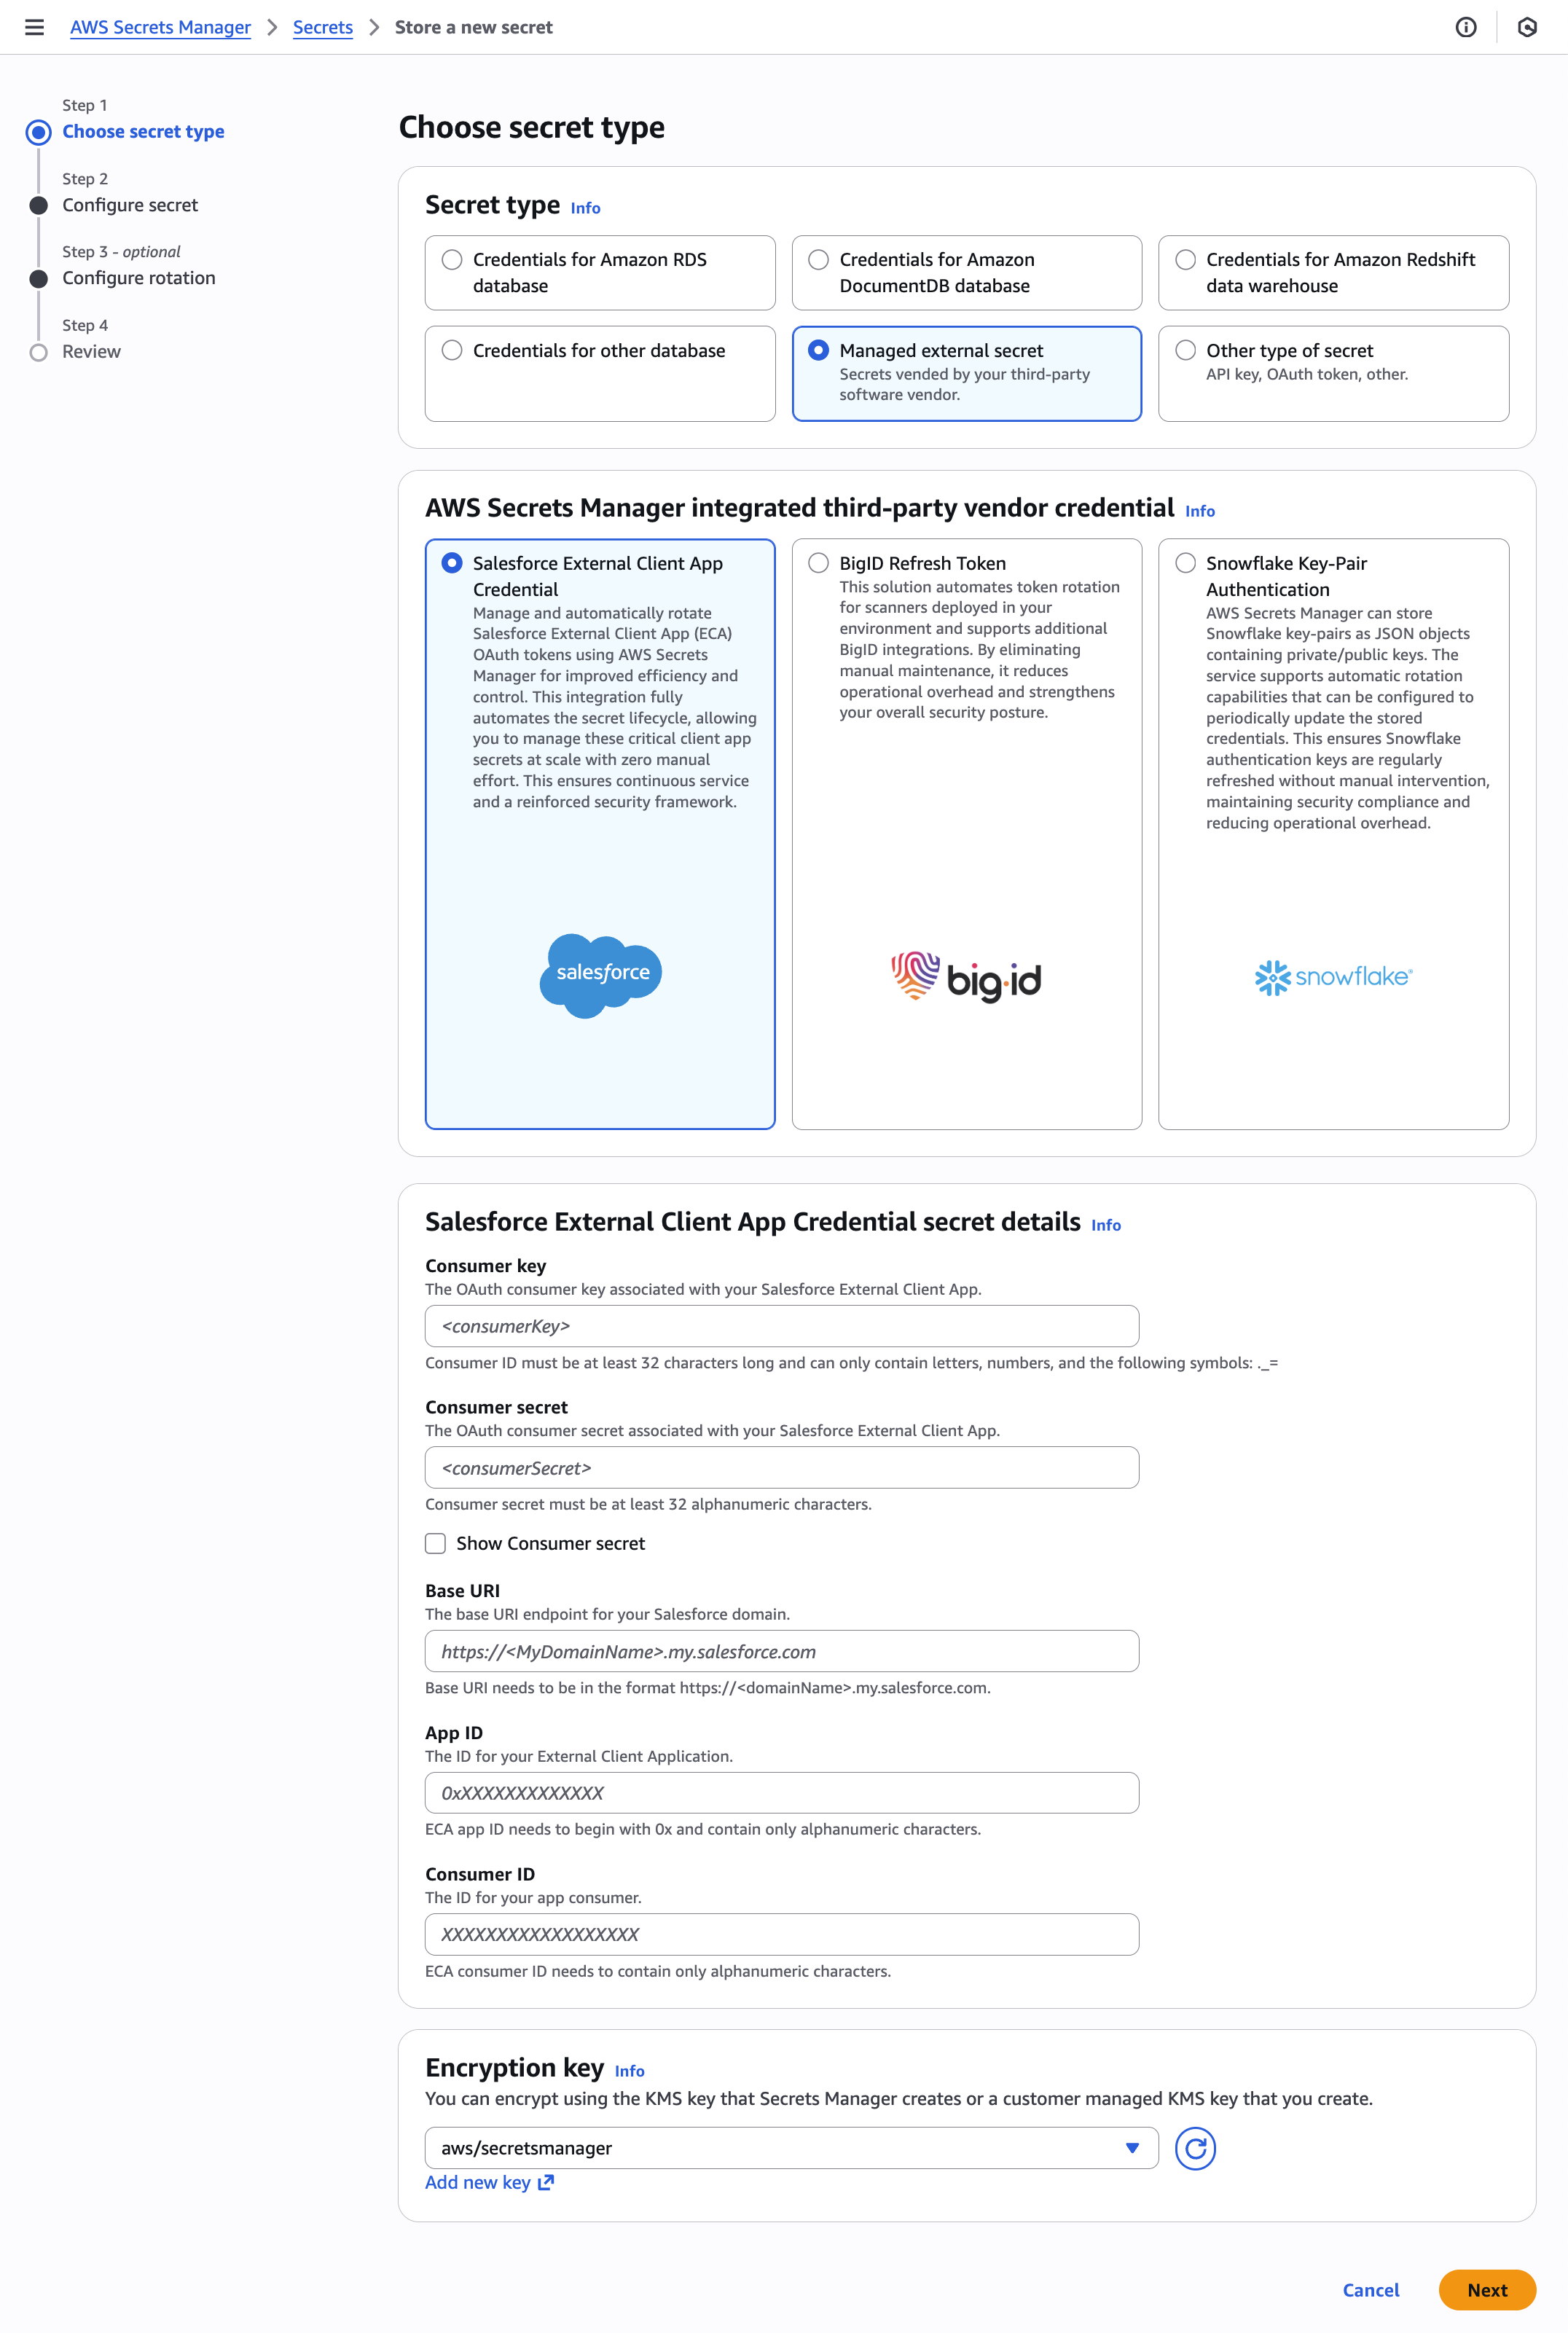
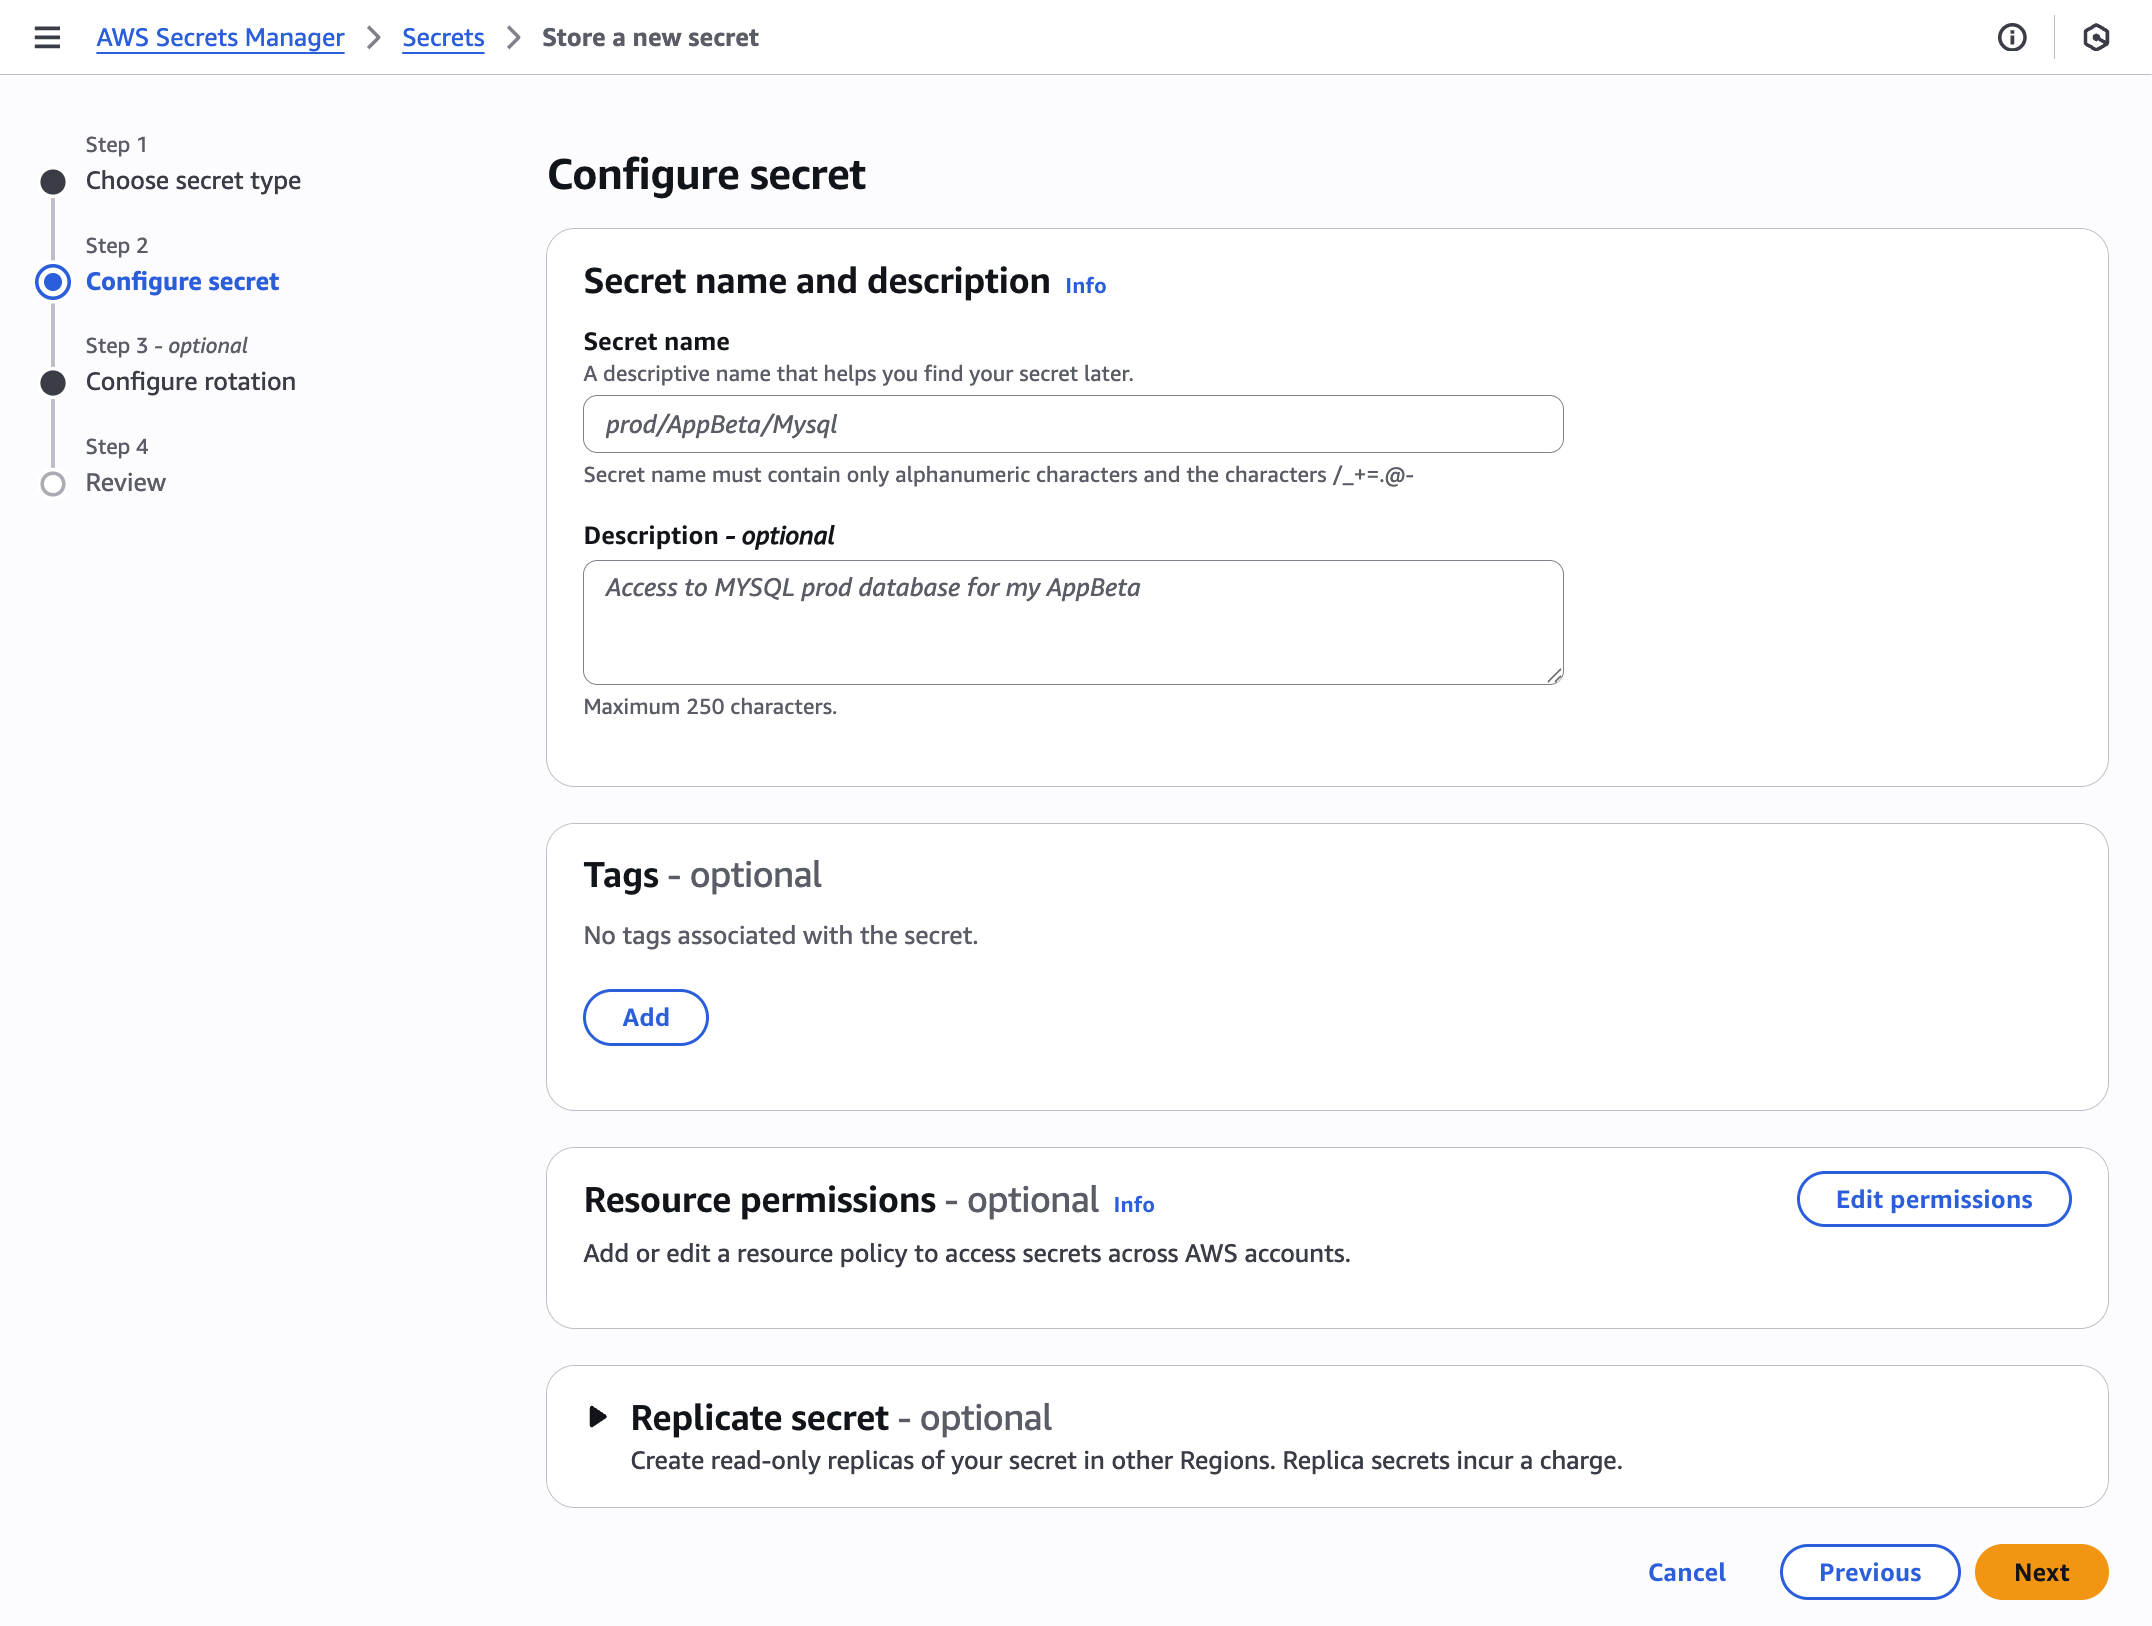
If you have feedback about this post, submit comments in the Comments section below.

Aaron Brown

Aaron Brown

Aaron Brown is a Senior AI Security Architect at AWS with over 8+ years of experience designing, building and shipping AI solutions in the offensive and defensive security domains.

Matt Saner

Matt Saner

Matt Saner is a global security leader helping customers unblock and accelerate complex security challenges. He plays a key role in the development of security standards for AI, including serving on the project governing board and executive steering committee for the Coalition for Secure AI (CoSAI) and as a distinguished review board member for OWASP’s GenAI and Agentic AI security projects.

Introducing attribute-based access control for Amazon S3 general purpose buckets

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/introducing-attribute-based-access-control-for-amazon-s3-general-purpose-buckets/

As organizations scale, managing access permissions for storage resources becomes increasingly complex and time-consuming. As new team members join, existing staff changes roles, and new S3 buckets are created, organizations must constantly update multiple types of access policies to govern access across their S3 buckets. This challenge is especially pronounced in multi-tenant S3 environments where administrators must frequently update these policies to control access across shared datasets and numerous users.

Today we’re introducing attribute-based access control (ABAC) for Amazon Simple Storage Service (S3) general purpose buckets, a new capability you can use to automatically manage permissions for users and roles by controlling data access through tags on S3 general purpose buckets. Instead of managing permissions individually, you can use tag-based IAM or bucket policies to automatically grant or deny access based on tags between users, roles, and S3 general purpose buckets. Tag-based authorization makes it easy to grant S3 access based on project, team, cost center, data classification, or other bucket attributes instead of bucket names, dramatically simplifying permissions management for large organizations.

How ABAC works
Here’s a common scenario: as an administrator, I want to give developers access to all S3 buckets meant to be used in development environments.

With ABAC, I can tag my development environment S3 buckets with a key-value pair such as environment:development and then attach an ABAC policy to an AWS Identity and Access Management (IAM) principal that checks for the same environment:development tag. If the bucket tag matches the condition in the policy, the principal is granted access.

Let’s see how this works.

Getting started
First, I need to explicitly enable ABAC on each S3 general purpose bucket where I want to use tag-based authorization.

I navigate to the Amazon S3 console, select my general purpose bucket then navigate to Properties where I can find the option to enable ABAC for this bucket.

I can also use the AWS Command Line Interface (AWS CLI) to enable it programmatically by using the new PutBucketAbac API. Here I am enabling ABAC on a bucket called my-demo-development-bucket located in the US East (Ohio) us-east-2 AWS Region.

aws s3api put-bucket-abac --bucket my-demo-development-bucket abac-status Status=Enabled --region us-east-2

Alternatively, if you use AWS CloudFormation, you can enable ABAC by setting the AbacStatus property to Enabled in your template.

Next, let’s tag our S3 general purpose bucket. I add an environment:development tag which will become the criteria for my tag-based authorization.

Now that my S3 bucket is tagged, I’ll create an ABAC policy that verifies matching environment:development tags and attach it to an IAM role called dev-env-role. By managing developer access to this role, I can control permissions to all development environment buckets in a single place.

I navigate to the IAM console, choose Policies, and then Create policy. In the Policy editor, I switch to JSON view and create a policy that allows users to read, write and list S3 objects, but only when they have a tag with a key of “environment” attached and its value matches the one declared on the S3 bucket. I give this policy the name of s3-abac-policy and save it.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "s3:GetObject",
                "s3:PutObject",
                "s3:ListBucket"
            ],
            "Resource": [
                "*"
            ],
            "Condition": {
                "StringEquals": {
                    "aws:ResourceTag/environment": "development"
                }
            }
        }
    ]
}

I then attach this s3-abac-policy to the dev-env-role.

That’s it! Now a user assuming the dev-role can access any ABAC-enabled bucket with the tag environment:development such as my-demo-development-bucket.

Using your existing tags
Keep in mind that although you can use your existing tags for ABAC, because these tags will now be used for access control, we recommend reviewing your current tag setup before enabling the feature. This includes reviewing your existing bucket tags and tag-based policies to prevent unintended access, and updating your tagging workflows to use the standard TagResource API (since enabling ABAC on your buckets will block the use of the PutBucketTagging API). You can use AWS Config to check which buckets have ABAC enabled and review your usage of PutBucketTagging API in your application using AWS Cloudtrail management events.

Additionally, the same tags you use for ABAC can also serve as cost allocation tags for your S3 buckets. Activate them as cost allocation tags in the AWS Billing Console or through APIs, and your AWS Cost Explorer and Cost and Usage Reports will automatically organize spending data based on these tags.

Enforcing tags on creation
To help standardize access control across your organization, you can now enforce tagging requirements when buckets are created through service control policies (SCPs) or IAM policies using the aws:TagKeys and aws:RequestTag condition keys. Then you can enable ABAC on these buckets to provide consistent access control patterns across your organization. To tag a bucket during creation you can add the tags to your CloudFormation templates or provide them in the request body of your call to the existing S3 CreateBucket API. For example, I could enforce a policy for my developers to create buckets with the tag environment=development so all my buckets are tagged accurately for cost allocation. If I want to use the same tags for access control, I can then enable ABAC for these buckets.

Things to know

With ABAC for Amazon S3, you can now implement scalable, tag-based access control across your S3 buckets. This feature makes writing access control policies simpler, and reduces the need for policy updates as principals and resources come and go. This helps you reduce administrative overhead while maintaining strong security governance as you scale.

Attribute-based access control for Amazon S3 general purpose buckets is available now through the AWS Management Console, API, AWS SDKs, AWS CLI, and AWS CloudFormation at no additional cost. Standard API request rates apply according to Amazon S3 pricing. There’s no additional charge for tag storage on S3 resources.

You can use AWS CloudTrail to audit access requests and understand which policies granted or denied access to your resources.

You can also use ABAC with other S3 resources such as S3 directory bucket, S3 access points and S3 tables buckets and tables. To learn more about ABAC on S3 buckets see the Amazon S3 User Guide.

You can use the same tags you use for access control for cost allocation as well. You can activate them as cost allocation tags through the AWS Billing Console or APIs. Check out the documentation for more details on how to use cost allocation tags.

Introducing the Landing Zone Accelerator on AWS Universal Configuration and LZA Compliance Workbook

Post Syndicated from Kevin Donohue original https://aws.amazon.com/blogs/security/introducing-the-landing-zone-accelerator-on-aws-universal-configuration-and-lza-compliance-workbook/

We’re pleased to announce the availability of the latest sample security baseline from Landing Zone Accelerator on AWS (LZA)—the Universal Configuration. Developed from years of field experience with highly regulated customers including governments across the world, and in consultation with AWS Partners and industry experts, the Universal Configuration was built to help you implement security and compliance at scale for on your regulated workloads. By setting a high bar with the latest AWS security best practices, the Universal Configuration can help address technical control requirements from compliance frameworks across different geographic regions and industry verticals. The Universal Configuration’s multi-account security architecture provides a foundation to host your diverse workload requirements today along with providing the ability to explore the generative AI and agentic AI solutions that will shape your organization in the future. It can also replace months of complex planning and design by deploying a comprehensive security and compliance-driven environment based on AWS Well-Architected principles in a matter of hours.

As organizations grow, they typically pursue or must adhere to new security compliance certifications. LZA and the Universal Configuration help organizations of all sizes and phases in their security and compliance journey. The speed of deployment, step-by-step documentation, and compliance resources can reduce traditional assessment and authorization timelines by months and result in more predictable and successful audit outcomes. This enables more freedom to invest resources to grow the business instead of choosing between security and compliance tradeoffs.

The Universal Configuration helps organizations:

  • Automate the deployment of a secure multi-account AWS environment
    • Foundational security controls based on AWS Well-Architected best practices
    • Apply consistent and predictable security controls post-deployment
    • Enable and integrate with native AWS security, identity, and compliance services
  • Implement controls across system layers
    • Organization-wide security architecture
    • Perimeter and resource-specific preventative, proactive, and detective controls
    • Support for multi-AWS Region resilience, disaster recovery, and active failover
  • Establish a foundation for security and compliance readiness
    • Built-in AWS security best practices and technical implementation statements
    • Map LZA capabilities across global and industry-specific compliance frameworks
    • Deploy hundreds of controls hours instead of months

The LZA Compliance Workbook

The LZA engine has been a trusted tool for quickly deploying secure multi-account AWS environments for over 4 years. It is also cost effective because you pay only for the AWS services used to operate your environment. The Universal Configuration is the first sample configuration accompanied by the LZA Compliance Workbook available on AWS Artifact. It’s a first-of-its-kind resource with detailed control mappings showing how the Universal Configuration can help you address requirements from frameworks including NIST 800-53 Rev5, CMMC/NIST 800-171, ISO-27001, HIPAA, C5:2020, NATO D-32 (Appendix B), and DoD CCI.

The LZA Compliance Workbook is regularly maintained to reflect the latest Universal Configuration baseline and will include additional compliance mappings in future releases. The workbook contains detailed security configuration descriptions based on the Universal Configuration deployment files, along with control requirement mappings and implementation statements that translate its security capabilities into a compliance-friendly format. By combining AWS security best practices with global compliance expertise, the Universal Configuration delivers predicable security outcomes while also helping you meet regional and industry requirements.

Getting started

To get started with the Landing Zone Accelerator on AWS Universal Configuration, the LZA Implementation Guide walks you through the steps, use cases, and considerations when deploying with LZA. You can download the LZA Compliance Workbook from AWS Artifact today and configure notifications to receive emails when future versions are released. You can view the deployment files and additional technical implementation guidance on the GitHub Universal Configuration sample and documentation page. Additionally, visit the AWS Partner Network (APN) for help with audit and advisory initiatives, cloud migrations, deploying the LZA Universal Configuration, and other services. You can visit the AWS Partner Finder tool and search by solution for Landing Zone Accelerator for the latest LZA Partner offerings.

If you have feedback about this post, submit comments in the Comments section below.

Kevin Donohue

Kevin Donohue

Kevin is a Senior Security Compliance Engineer at AWS, where he builds solutions and resources to help AWS customers achieve their security and compliance goals. Prior to joining the Landing Zone Accelerator team in AWS Professional Services in 2024, Kevin began his tenure with AWS Security in 2019 specializing in FedRAMP compliance and the shared responsibility model.

Christine Screnci

Christine Screnci

Christine is a Principal Technical Product Manager at AWS, where she specializes in developing and scaling enterprise-level solutions. Christine began her tenure with AWS in 2016 working with Worldwide Public Sector customers to improve the migration and modernization journey through globally scaled solutions. She is passionate about hypothesis-driven development and experimentation to improve customer experiences with AWS technologies.

Bhavish Khatri

Bhavish is a Senior Delivery Engineer at AWS, where he builds enterprise-scale solutions to help large organizations achieve their compliance goals. Bhavish started at AWS in 2018, specializing in multi-account AWS deployments and focusing on LZA and the Universal Configuration solution. He helps organizations build secure, scalable cloud environments that align with global compliance frameworks and regulatory requirements across diverse sectors.

Transfer data across AWS partitions with IAM Roles Anywhere

Post Syndicated from Jennifer Paz original https://aws.amazon.com/blogs/security/transfer-data-across-aws-partitions-with-iam-roles-anywhere/

Transfer across AWS Cloud partitions. Different identity planes. Long-lived IAM user credentials.

As an enterprise customer, you might need to bring together security, operational, and compliance data from multiple AWS partitions. Creating a holistic view of these types of data is critical to support operations and applications but understanding how to accomplish this while maintaining compliance can be a challenge.

In this post, we show you a past method for securing cross-partition data movement using AWS Identity and Access Management (IAM) user keys and why that’s no longer recommended. We continue by showing you the recommended best practice of using AWS IAM Roles Anywhere to support cross-partition data movement.

Security and compliance and AWS Regions and partitions

Before you begin, it’s important to understand how AWS Regions and partitions are designed. AWS partitions are hard boundaries designed to meet isolation requirements for compliance purposes and consist of one or more Regions, with each partition controlled by an independent instance of IAM. AWS provides multiple partitions; AWS Commercial Regions use an aws partition identifier within the Amazon Resource Name (ARN), AWS GovCloud Regions use an aws-us-gov partition identifier, and the AWS China Regions use an aws-cn partition identifier. AWS account IDs and Region designations are reserved to make sure that they exist only within that respective AWS partition. The IAM instance profile, within each AWS partition, prohibits the creation of trust policies that cross partitions. If you attempt to construct a cross-account trust policy across two partitions, they will receive a CREATE_FAILED error as shown in Figure 1. This isolation between partitions is part of the security that we provide our customers.

Figure 1: Failure message for cross partition trust policy

Figure 1: Failure message for cross partition trust policy

It’s critical that you understand your compliance requirements and build a unified dashboard and workflows in the appropriate partition. For example, data should only flow from the AWS Commercial partition to the AWS GovCloud partition—not the other way around. To adhere to the FedRAMP boundary policy FRR211, data about workloads within the AWS GovCloud partition should not be shared with AWS Commercial partition. Thus, it’s a best practice when you create a unified dashboard and automation to design the architecture and solution to operate within the AWS GovCloud partition. This approach enables a consolidated view of your security and cloud operations. From this centralized data plane, automated remediations, notifications, and escalations can be triggered by using Amazon EventBridge against data collected from Commercial and GovCloud Regional resources. These automated workflows can be used for operational triage within a ticketing system (such as Service Now or Atlassian JIRA), security detections within a cloud-native application protection platform (CNAPP) (such as AWS Security Hub or CrowdStrike), and application alerting from enterprise notification systems (such as Slack, Microsoft Teams, or email).

In addition to data partition isolation, it’s a FedRAMP security best practice to make sure that the credentials used to access GovCloud Regions are isolated to exist only within those Regions. It’s also a best practice to make sure that data access requests originate from the GovCloud partition, and to pull data from the less restrictive partition, such as the aws Commercial partition. This requirement is designed to help prevent exposure of GovCloud partition resources to the Commercial partition through open ports, APIs, endpoints, or credentials to a commercial partition. Because AWS Commercial partition resources can support connectivity from the internet, you can put appropriate security controls to limit access to endpoints, ports, APIs and load balancers using short-term or long-term credentials.

Cross-partition data transfer using IAM access keys (Not recommended)

Though this is no longer a recommended best practice, data transfer requirements were met previously by using Data Sync, s3api, data transfer hub, and other SDK methods by creating an IAM user access key in the AWS Commercial partition. You would then store the aws partition IAM user access key in AWS Secrets Manager in the aws-us-gov partition. By using this method, one of these applications would operate within AWS GovCloud; the application would then use the aws partition IAM user access key to access and read data from the commercial partition Amazon Simple Storage Service (Amazon S3) bucket and then write it to the AWS GovCloud Partition S3 bucket. The application could then process the data within the application running in the AWS GovCloud partition. That legacy architecture is shown in Figure 2.

Figure 2: Cross-partition data movement using IAM access keys

Figure 2: Cross-partition data movement using IAM access keys

This solution requires an audit exception to allow the use of long-term user credentials. Using long-term user credentials for workloads or service accounts deviates from AWS security best practices and NIST 800-53 IA2, because they can be compromised and difficult to rotate and change. Temporary credentials align with AWS security best practices and are provided by AWS roles. Additionally, the use of x509 certificates has been a standard for establishing secure communications with applications operating processes on remote devices and comply with NIST 800.53r5 IA8.

Cross-partition data transfer using IAM Roles Anywhere (Recommended)

To meet the requirement to use short-term credentials and enable access across an AWS partition, you can use IAM Roles Anywhere, which avoids the need for long-term access key or secret access key credentials. Using IAM Roles Anywhere, you can use your existing certificate authority (CA) or AWS Private Certificate Authority to issue and manage X.509 certificates to specific workloads and applications. You can register your external CA with IAM Roles Anywhere as a trust anchor to establish a trust between your external CA and IAM Roles Anywhere. If you don’t manage your own private key infrastructure (PKI), a trust can be established with AWS Private CA to create a CA as the trust anchor. For detailed steps for setting up IAM Roles Anywhere, see Planning for your IAM Roles Anywhere deployment.

Figure 3: Architecture for cross-partition data movement using IAM Roles Anywhere with an external CA

Figure 3: Architecture for cross-partition data movement using IAM Roles Anywhere with an external CA

Figure 3 demonstrates how you can use IAM Roles Anywhere with an external CA to enable data transfer between partitions. By using this pattern, which is an AWS security best practice, you can pull data from your AWS Commercial partition into your AWS GovCloud partition. By using an external CA, you can use your existing PKI. For compliance purposes, internal CAs are often required to issue certificates for internal applications and services, device authentication, internal web services, employee authentication, and other tasks. Internal PKI consists of a root CA, intermediate CA and an issuing CA. The root CA is often disconnected from the internet to help prevent tampering or issuing of PKI to untrusted resources. The root CA will issue a certificate for an intermediate CA and the intermediate CA will create certificates for one or more issuing CAs. When the GovCloud application creates a certificate signing request (CSR), it will maintain the private key that goes with the CSR in Secrets Manager. The customer’s external issuing CA will then sign the CSR and provide an end-entity certificate for the GovCloud application in addition to the external CA bundle. This CA bundle contains the root CA, intermediate CA, and issuing CA certificates. All three of which will be stored in GovCloud application’s Secrets Manager so that the workload can then interact with AWS Commercial partition resources.

As shown in Figure 3 you can initiate a temporary session from GovCloud (right) to AWS Commercial (left). IAM Roles Anywhere is configured within the Commercial partition to use your existing PKI as the trust anchor. As you vend PKI certificates to workloads that run in GovCloud, they’re stored in Secrets Manager, and your Amazon Elastic Kubernetes Service (Amazon EKS) role allows access to the certificates. In the Commercial Region, you configured a role that allows access to Amazon Simple Notification Service (Amazon SNS), Amazon Simple Queue Service (Amazon SQS), and Amazon S3. You then configure the trust policy on that role to allow IAM Roles Anywhere access. Based on your GovCloud application scheduling, the Amazon EKS pipeline provides the credential helper process temporary security credentials for the Commercial Region. It does this by using the certificates, private key, Commercial Region IAM Roles Anywhere role ARN, profile ARN, and trust anchor ARN that are provided to the GovCloud application as it prepares to connect from the GovCloud Region to the Commercial Region.

Figure 4: Cross-partition data movement using IAM Roles Anywhere with AWS Private CA

Figure 4: Cross-partition data movement using IAM Roles Anywhere with AWS Private CA

If you don’t have an existing PKI in place, or don’t want to build your own offline PKI, you can use AWS Private CA, as shown if Figure 4. Using AWS Private CA, you don’t have to maintain hardware or software. As a managed service, AWS handles the high availability, scalability, and durability, in addition to patching and maintenance. You also benefit from seamless integration with other AWS services such as AWS Elastic Load Balancing, Amazon CloudFront, and Amazon API Gateway. AWS Private CA also integrates with AWS CloudTrail, so that you can audit what actions have been taken.

Conclusion

In this post, we explained the compliance requirements that need to be considered when migrating data across AWS partitions. We also outlined architectural options AWS customers and partners can take when implementing a solution to address this need.

IAM Roles Anywhere is a great solution that AWS Customers and software as a service (SaaS) partners can use when they want to access AWS resources from across AWS partitions without needing to use long-lived credentials for IAM users.

To learn more about IAM Roles Anywhere, see the feature’s documentation, this IAM Roles Anywhere workshop, or this re:Inforce presentation featuring Hertz.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS Security, Identity, and Compliance re:Post or contact AWS Support.

If you have feedback about this post, submit comments in the Comments section below.

Jenn Reed

Jenn Reed

Jenn is Principal Security Solutions Architect at AWS and former CISO, with over 30 years of security and software development experience and 12 years of experience building on AWS. She lives in Ann Arbor, Michigan, and enjoys running, playing ukulele, and reading science fiction novels.

Bill Wells

Bill Wells

Bill is a Senior Solutions Architect at AWS with over 20 years of experience beginning in the U.S. Air Force. Leveraging his diverse IT background across multiple organizations, Bill specializes in architecting secure, compliance-aligned cloud solutions that help Federal Partners achieve business outcomes using AWS services.

How to update CRLs without public access using AWS Private CA

Post Syndicated from Rochak Karki original https://aws.amazon.com/blogs/security/how-to-update-crls-without-public-access-using-aws-private-ca/

Certificates and the hierarchy of trust they create are the backbone of a secure infrastructure. AWS Private Certificate Authority is a highly available certificate authority (CA) that you can use to create private CA hierarchies, secure your applications and devices with private certificates, and manage certificate lifecycles.

A certificate revocation list (CRL) is a file that contains a signed list of certificates revoked before their scheduled expiration date. Certificates can be revoked for a variety of reasons, including unintended key exposure, or because of discontinued use.

AWS Private CA writes CRLs to an Amazon Simple Storage Service (Amazon S3) bucket that you specify. CRLs are public, fully qualified domain names (FQDNs), but you might have requirements for a CRL that is only accessible internally to your organization, or you might have security standards that require all S3 buckets to have Amazon S3 block public access enabled.

The recommended practice for S3 buckets is to enable Block Public Access, which enables only authorized and authenticated AWS accounts to have access to a bucket and its contents. However, because some public key infrastructure (PKI) clients retrieve CRLs across the public internet, a workaround might be necessary to serve CRLs without requiring authenticated client access to an S3 bucket. One recommended solution is to use Amazon CloudFront to provide access to the CRL. This will likely be the best solution for most customers. Our documentation specifically highlights CloudFront as the recommended implementation path. However, you might not be able to use CloudFront or might need another option.

You might need a solution where the CRL lookups don’t traverse the public internet. In this post, we go over two different approaches to achieve this.

Option 1: Relocate CRLs to an internally accessible location

By default, AWS Private CA writes CRLs to an S3 bucket that you specify. This solution consists of moving the CRL to a separate location that is internally accessible to your TLS clients, but not accessible via the public internet such as an on-premises server. A CRL distribution point (CDP) is a link that points to the location of the CRL where revoked certificates appear. However, when private certificates are generated by AWS Certificate Manager (ACM), the CDP universal resource identifiers (URI) in the certificates point by default to the S3 bucket initially specified.

This solution uses a custom CNAME in the CDP to indicate, during certificate generation, the location where the CRL will ultimately be located.

The steps in the solution are as follows:

  1. Select the S3 bucket where the CRL will be stored.
  2. Issue a certificate through the CA with a custom CNAME.
  3. Create an AWS Lambda function that moves the CRL file from the S3 bucket to another specified location.
  4. Create an Amazon Simple Notification Service (Amazon SNS) notification that alerts a user to the success metric of the CRL generation event.

Prerequisites:

For this walkthrough, you must have the following resources ready to use:

  1. An AWS account with:
    • An AWS Identity and Access Management (IAM) role with permissions for Amazon S3, ACM Private CA, Amazon EventBridge, and Lambda
    • An ACM private CA root and subordinate CA configured in the same AWS Region
    • An S3 bucket for the CRL with permissions that allow the AWS Private CA service principal to PutObject, PutObjectACL, GetBucketACL and GetBucketLocation (see the following example bucket policy)
{     
    "Version": "2012-10-17",     
    "Statement": [         
        {             
            "Effect": "Allow",             
            "Principal": {                 
                "Service": "acm-pca.amazonaws.com"             
            },             
            "Action": [                 
                "s3:PutObject",                 
                "s3:PutObjectAcl",                 
                "s3:GetBucketAcl",                 
                "s3:GetBucketLocation"             
            ],             
            "Resource": [                 
                "arn:aws:s3:::<name-of-bucket>/*",                 
                "arn:aws:s3:::<name-of-bucket>"             
            ],             
            "Condition": {                 
                "StringEquals": {                     
                    "aws:SourceAccount": "<account-num-here>",                     
                    "aws:SourceArn": "<subordinate-ca-arn-here>"                 
                }             
            }         
        }     
    ] 
}

2. AWS Command Line Interface (AWS CLI) configured

Deploy:

With the prerequisites in place, you’re ready to deploy the first solution.

To enable CRL distribution:

  1. Use your account to sign in to the AWS Management Console for AWS Private Certificate Authority.
  2. Select the name of your subordinate CA. This should take you to another page with more details.
  3. Scroll down and choose the Revocation configuration tab.
  4. Choose Edit on the top right.
  5. Figure 1: Edit the revocation configuration

    Figure 1: Edit the revocation configuration

  6. Select Activate CRL distribution. Select the CRL S3 bucket you created prior to the walkthrough.
  7. Figure 2: Enter a name for your CRL

    Figure 2: Enter a name for your CRL

  8. Modify the CDP by expanding the CRL settings dropdown. In the Custom CRL Name field, enter the URL where you will eventually move the CRL. This should be a place that is accessible by your internal organization, but not accessible externally. If you use partitioned CRLs, select the Enable partitioning checkbox. To learn more about CRL partitioning, see Plan your AWS Private CA certificate revocation method.
  9. Choose Save changes.

To create an SNS topic and Lambda function:

  1. Go to the Amazon SNS console.
  2. Create a standard SNS topic. Leave all options as default and subscribe an appropriate email to the topic.
  3. Figure 3: Create an SNS topic

    Figure 3: Create an SNS topic

  4. Go to the Lambda console.
  5. Choose Create Function.
  6. Enter a name for your function. Under Runtime, select Python 3.12 from the dropdown.
  7. Figure 4: Create a Lambda function

    Figure 4: Create a Lambda function

  8. Verify that the role associated with your Lambda function has permissions to get objects from the S3 bucket where AWS Private CA places the CRL (set when you configured the revocation details for the CA), copy objects in Amazon S3, then put objects in an S3 bucket (or wherever the new CRL distribution point specified in the certificate custom CNAME will be—for example, an internal-only accessible location), and publish to an Amazon SNS topic. The Lambda function also checks the success metric of a CRL generation event. If the event fails, an SNS topic will notify an admin. If the event is successful, a copy of the CRL in the original S3 bucket is created in the new specified location and an SNS topic will notify an admin.

Example code (Python 3.13):

import boto3 
import json 

def lambda_handler(event, context):     
	#create a s3 client     
	s3 = boto3.client('s3')          

	#create a sns client     
	sns = boto3.client('sns')     
    topicArn = "<sns-topic-arn-here>”     
    
    #get name of the CA from the CW event     
    caID = event['resources'][0].split('/')[-1]          
    status = event['detail']['result']     
    if status == 'success':              
    	
        source = '<ORIGINS3BUCKET>'         
        destination = '<DESTINATION-S3BUCKET>'         
        #See below note for more clarification on S3 CRL paths         
        folder = 'crl/'         
        file = caID + '.crl'         
        key = folder + file              
        
        try:             
        	copySource = {                 
            	'Bucket': source,                 
                'Key': key             
           	}                      
            
            s3.copy_object(                 
            	CopySource=copySource,                 
                Bucket=destination,                 
                Key=file             
          	)             
            response = sns.publish(                 
            	TopicArn=<sns-topicArn>,                 
                Message=f'Successfully moved {key} from {source} to {destination} in {caID}',                 
                Subject="CRL Upload Success"             
          	)                      
            
            return {                 
            	'statusCode': 200,                 
                'body': json.dumps(f'Successfully moved {key} from {source} to {destination} in {caID}')             
          	}                  
    	
        except s3.exceptions.NoSuchKey:             
        	response = sns.publish(                 
            	TopicArn=<sns-topicArn>,                 
                Message=f"Object {key} not found in {source}",                 
                Subject='CRL Upload Failure'             
          	)             
            return {                 
            	'statusCode': 404,                 
                'body': json.dumps(f'Object {key} not found in {source}')             
          	}                  
   		except Exception as e:             
    		print(e)             
        	response = sns.publish(                 
        		TopicArn=<sns-topicArn>,                 
            	Message=f'Error moving object: {str(e)}',                 
            	Subject='Failure Uploading CRL'             
     		)             
			return {                 
    			'statusCode': 500,                 
        		'body': json.dumps(f'Error moving object: {str(e)}')             
  			}     
    else:         
    	response = sns.publish(                 
        		TopicArn=<sns-topicArn>,                 
            	Message=f'Certificate Authority {caID} CRL creation {status}',                 
            	Subject='CRL Upload Failure'             
     		)         
        return {             
        	'statusCode': 200,             
            'body': json.dumps(f'Certificate Authority {caID} CRL creation {status}')         
      	}

Note: By default, the non-partitioned CRL path in S3 is <s3-bucket-name>/crl/<CA-ID>.crl. If you used a custom path, modify the path name to the CRL accordingly. Alternatively, if using partitioned CRLs, the path changes to <s3-bucket-name>/crl/<CA-ID>/<partition_GUID>.crl; in that case, you can loop over each file in the <CA-ID> path to achieve the same effect.

To create an EventBridge that deploys your Lambda function:

  1. Go to the EventBridge console. Under Buses, select Rules.
  2. Choose Create Rule.
  3. Enter a name for your rule. Under Rule Type, select Rule with an Event Pattern and choose Next.
  4. Under Events, select AWS events or EventBridge partner events as the Event Source.
  5. For the Event pattern, select Use pattern form. For the Event source, select AWS services. For Event Type, select ACM Private CA CRL Generation.
Figure 5: Configure the event pattern

Figure 5: Configure the event pattern

  1. Choose Next.
  2. Under Target types, choose AWS Service, and then select Lambda function from the Select a target dropdown and select the function that you created earlier.
  3. Figure 6: Select the Lambda function as the target

    Figure 6: Select the Lambda function as the target

  4. Choose Next. Review your topic, then choose Update rule.
  5. To test the success of the Lambda function:

    1. To test the EventBridge topic, create and revoke a certificate. You can do this using the AWS CLI by getting the serial number of a certificate using openSSL:
      openssl x509 -in cert.pem -noout -serial
    2. Use the following command to revoke the certificate:
      aws acm-pca revoke-certificate —certificate-authority-arn <CA ARN> \ —certificate-serial <SERIAL NUMBER RETURNED IN STEP 1> --revocation-reason “UNSPECIFIED”
    3. To make sure that the Lambda function is triggered, wait 5–30 minutes. Check CloudTrail to make sure that RevokeCertificate was called, then monitor the CloudWatch log of the Lambda function. You should also get a notification message from your SNS topic.
    4. You have now successfully moved your CRL to a new location.

    Option 2: Implement Private CRL Access Through AWS Private CA

    This solution provides private Certificate CRL access within AWS Private CA, avoiding the need for public internet exposure. The design centers on establishing root and subordinate CAs with CRL functionality enabled within a dedicated S3 bucket, combined with a private network infrastructure using Gateway VPC endpoints and private subnets. Security is enforced through an S3 bucket policy that accomplishes three critical objectives:

    • Authorizing essential AWS Private CA permissions
    • Constraining CRL access to a designated Gateway VPC endpoint
    • Explicitly blocking access attempts from other sources.

    The solution includes private DNS zone configuration for proper resolution and can be verified through access testing confirming successful CRL retrieval from private VPC instances while making sure that requests from public instances are denied, maintaining a strictly private PKI.

    1. Create a root CA and subordinate CA with CRL enabled
    2. Configure a dedicated S3 bucket for CRL storage
    3. Issue private certificates through ACM
    4. Set up a VPC with private subnets
    5. Configure a Gateway VPC endpoint for Amazon S3
    6. Set up route tables for local traffic only
    7. Implement an S3 bucket policy with specific permissions
    8. Configure private DNS resolution
    9. Set up access controls through VPC endpoints
    10. Test private access from within the VPC
    11. Verify that public access is blocked

    Prerequisites for CRL solution 2

    For this walkthrough, you must have the following resources available:

    Deploy CRL solution 2

    With the prerequisites in place, you’re ready to use the console and AWS CLI to deploy the solution.

    To deploy the solution:

    1. Go to the AWS Private Certificate Authority console.
    2. In the navigation pane, choose Create a Private CA.
      1. Under Mode options, select General-purpose.
      2. For CA type options, select root.
      3. For the Subject distinguished name options: Fill in at least one of the subject distinguished name options: Organization(O), Organization unit (OU), Country(C), State, Locality name, and Common name (CN).
        Figure 7: Create a private CA (root)

        Figure 7: Create a private CA (root)

      4. Select Key algorithm options, for example, RSA 2046.
      5. Under Certificate revocation options, select Activate CRL Distribution, and select or create an S3 bucket for CRL storage.
      6. Under Pricing, select the checkbox to acknowledge pricing and then select Create CA.
    Figure 8: Configure a private CA (root)

    Figure 8: Configure a private CA (root)

    3. After creating a root CA, repeat all of step 2 to create a subordinate CA, selecting
    Subordinate CA under
    CA options (step 2-b). When completed, both the root CA and subordinate CA will be visible on the Private certificate authority page.

    Figure 9: View of root CA and subordinate CA

    Figure 9: View of root CA and subordinate CA

    With the root CA and subordinate CA in place, the next step is to create a VPC gateway endpoint for S3 access to enable private network communication.

    To create a VPC gateway endpoint:

    1. Go to the Amazon VPC console
    2. In the left navigation pane, select Endpoints, and choose Create Endpoint.
    3. Configure the Gateway VPC endpoint settings:
      1. Enter a descriptive name for your endpoint (optional).
      2. Type: Select AWS services.
      3. Services: Select the service name com.amazonaws.[region].s3 from the list.
      4. Type: Verify that Gateway is selected (automatically chosen for Amazon S3).
      5. VPC: Choose the VPC where you want to create the endpoint.
      6. Route tables: Select the route tables associated with the subnets that need Amazon S3 access.
      7. Policy: Select Full Access or create a custom policy to restrict access to specific S3 buckets or actions.
      8. Review your configuration and choose Create endpoint.
    Figure 10: Gateway VPC endpoint configuration

    Figure 10: Gateway VPC endpoint configuration

    1. Create two private subnets:
      1. In the Amazon VPC console, choose Subnets and then Create subnet.
      2. Select your VPC and enter the subnet details (name, Availability Zone, and CIDR block).
      3. Repeat for the second subnet in a different Availability Zone.
    2. Configure route tables:
      1. Navigate to Route Tables and choose Create route table.
      2. Create and name two route tables for your private subnets.
      3. Associate each route table with its corresponding private subnet.
      4. Make sure that each route table contains only local routes (VPC CIDR).
      5. Remove any routes for internet access (0.0.0.0/0).
    Figure 11: Private route table configuration

    Figure 11: Private route table configuration

    1. You can see now see under Resource Map that the Gateway VPC endpoint provides secure access to Amazon S3 resources within the private network.
    Figure 12: VPC private instance configuration

    Figure 12: VPC private instance configuration

    1. Use the following example code to implement a bucket policy that enforces the following key security controls:
      • Grant AWS Private CA the necessary permissions for certificate management.
      • Restrict CRL access exclusively through the specified VPC endpoint.
      • Explicitly deny GetObject requests not originating from the designated Gateway VPC endpoint.
    Figure 13: S3 bucket policy

    Figure 13: S3 bucket policy

    The following is an example S3 bucket policy for private CA CRL access with VPC endpoint restrictions:

    {     
        "Version": "2012-10-17",     
        "Statement": [         
            {             
                "Effect": "Allow",             
                "Principal": {                 
                    "Service": "acm-pca.amazonaws.com"             
                    },             
                "Action": [                 
                    "s3:PutObject",                 
                    "s3:PutObjectAcl",                 
                    "s3:GetBucketAcl",                 
                    "s3:GetBucketLocation"             
                ],             
                "Resource": [                 
                    "<arn:aws:s3:::BUCKET_NAME>",                 
                    "<arn:aws:s3:::BUCKET_NAME>/"           
                ],           
                "Condition": {               
                    "StringEquals": {                   
                        "aws:SourceArn": "<arn:aws:acm-pca:REGION:ACCOUNT_ID:certificate-authority/CA_ID>",                   
                        "aws:SourceAccount": "<ACCOUNT_ID>"               
                        }           
                }       
            },       
            {           
                "Sid": "Allow Access to CRL",           
                "Effect": "Allow",            
                "Principal": "",             
                "Action": "s3:GetObject",             
                "Resource": "<arn:aws:s3:::BUCKET_NAME/crl/CA_ID.crl>",             
                "Condition": {                 
                    "StringEquals": {                     
                        "aws:SourceVpce": "<VPCE_ID>"                 
                        }             
                }         
            },         
            {             
                "Sid": "Access-to-specific-VPCE-only",             
                "Effect": "Deny",             
                "Principal": "",            
                "Action": "s3:GetObject",           
                "Resource": [               
                    "<arn:aws:s3:::BUCKET_NAME>",               
                    "<arn:aws:s3:::BUCKET_NAME>/"             
                ],             
                "Condition": {                 
                    "StringNotEquals": {                     
                        "aws:SourceVpce": "<VPCE_ID>"                 
                        }             
                }         
            }     
        ] 
    }

    Figure 14: S3 bucket CRL properties

    Figure 14: S3 bucket CRL properties

    Create a private hosted zone:

    1. Go to the Route 53 console.
    2. In the left navigation pane, choose Hosted zones.
    3. Choose Create hosted zone.
    4. Configure the following:
      1. Domain name: Enter s3.amazonaws.com
      2. Description: (optional) enter Private hosted zone for S3 CRL endpoint
      3. Type: Select Private hosted zone.
      4. VPC: For Region, select your VPC’s Region; for VPC ID, select your VPC from the dropdown list.
    5. Choose Create hosted zone.

    Create a record set:

    1. Inside your new private hosted zone:
      1. Choose Create record.
      2. Select Simple routing policy.
      3. Choose Next.
    2. Configure record:
      1. Record name: Enter your S3 bucket name.
      2. Record type: Select A – Routes traffic to an IPv4 address.
      3. Alias: Toggle Yes.
      4. Route traffic to: Select Alias to S3 website endpoint.
      5. Region: Select your Region.
      6. S3 endpoint: Select from dropdown list.
      7. TTL: Leave as default (300 seconds).
    3. Choose Create record.
    Figure 15: Hosted zone details

    Figure 15: Hosted zone details

    Verify configuration:

    1. Go to the Amazon EC2 console and choose Launch instance.
    2. Select Amazon Linux 2.
    3. Choose Instance Type.
    4. Select you VPC and subnet.
    5. Under Network settings, select Create security group, then choose Allow SSH traffic from and enter your IP address.
    6. Choose Launch instance.
    7. After the instance is launched, select the instance and choose Connect.
    8. Select EC2 Instance Connect and choose Connect.

    Test the solution

    To test private access from an EC2 instance within your private VPC, verify CRL access using:
    curl -s https://<bucket-name>.s3.<region>.amazonaws.com/crl/<certificate-id>.crl | openssl crl -text -noout

    If successful, the command completes the following steps, as shown in Figure 16:

    1. Retrieves the CRL from Amazon S3
    2. Decodes it using OpenSSL
    3. Displays comprehensive CRL information including issuer details, update timestamps, revoked certificate list, signature algorithm, and other metadata
    Figure 16: Public access verification

    Figure 16: Public access verification

    To validate your security controls, attempt access from a public EC2 instance using the following command:
    curl https://<bucket-name>.s3.<region>.amazonaws.com/crl/<certificate-id>.crl

    This should fail, receiving an access denied error confirming that the CRL cannot be accessed from the public internet, as shown in Figure 17.

    Figure 17: Access denied error confirming that the CRL cannot be accessed from the public internet

    Figure 17: Access denied error confirming that the CRL cannot be accessed from the public internet

    Conclusion

    In this post, we walked you through two solutions that you can use to make your CRLs accessible to your internal organization, but not publicly available. First, we showed you how to configure a custom CNAME in your CRL distribution point and deploy Lambda functions to automatically copy each newly generated CRL from the default S3 bucket into a private S3 store.

    Next, we showed you a VPC architecture that uses an Amazon S3 VPC gateway endpoint, tightly scoped bucket policies, and private Route 53 DNS zones to make sure that CRL retrieval is confined to your VPC. We also covered the essential IAM and bucket policies that your clients need to access those CRLs securely. You can get started with setting up this solution on AWS Private CA today.

    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Certificate Manager forum or contact AWS Support.

Rochak Karki

Rochak Karki

Rochak is a Security Specialist Solutions Architect at AWS, focusing on threat detection, incident response, and data protection helping customers build secure environments. Rochak is a US Army veteran and holds a Bachelor of Science in Engineering from the University of Wyoming. Outside of work, he enjoys spending time with family and friends, hiking, and traveling.

Cheryl Wang

Cheryl is an Associate Security Solutions Architect at AWS based in the SF Bay Area. Cheryl is passionate about cybersecurity and helping customers improve their security infrastructure. She holds a B.A. in Computer Science from Wellesley College. Outside of work, she enjoys writing and playing guzheng.

Simplify access to external services using AWS IAM Outbound Identity Federation

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/simplify-access-to-external-services-using-aws-iam-outbound-identity-federation/

When building applications that span multiple cloud providers or integrate with external services, developers face a persistent challenge: managing credentials securely. Traditional approaches require storing long-term credentials like API keys and passwords, creating security risks and operational overhead.

Today, we’re announcing a new capability called AWS Identity and Access Management (IAM) outbound identity federation that customers can use to securely federate their Amazon Web Services (AWS) identities to external services without storing long-term credentials. You can now use short-lived JSON Web Tokens (JWTs) to authenticate your AWS workloads with a wide range of third-party providers, software-as-a-service (SaaS) platforms and self-hosted applications.

This feature enables IAM principals—such as IAM roles and users—to obtain cryptographically signed JWTs that assert their AWS identity. External services, such as third-party providers, SaaS platforms, and on-premises applications, can verify the token’s authenticity by validating its signature. Upon successful verification, you can securely access the external service.

How it works
With IAM outbound identity federation, you exchange your AWS IAM credentials for short-lived JWTs. This mitigates the security risks associated with long-term credentials while enabling consistent authentication patterns.

Let’s walk through a scenario where your application running on AWS needs to interact with an external service. To access the external service’s APIs or resources, your application calls the AWS Security Token Service (AWS STS) `GetWebIdentityToken` API to obtain a JWT.

The following diagram shows this flow:

  1. Your application running on AWS requests a token from AWS STS by calling the GetWebIdentityToken API. The application uses its existing AWS credentials obtained from the underlying platform (such as Amazon EC2 instance profiles, AWS Lambda execution roles, or other AWS compute services) to authenticate this API call.
  2. AWS STS returns a cryptographically signed JSON Web Token (JWT) that asserts the identity of your application.
  3. Your application sends the JWT to the external service for authentication.
  4. The external service fetches the verification keys from the JSON Web Key Set (JWKS) endpoint to verify the token’s authenticity.
  5. The external service validates the JWT’s signature using these verification keys and confirms the token is authentic and was issued by AWS.
  6. After successful verification, the external service exchanges the JWT for its own credentials. Your application can then use these credentials to perform its intended operations.

Setting up AWS IAM outbound identity federation
To begin using this feature, I need to enable outbound identity federation for my AWS account. I navigate to IAM and choose Account settings under Access management in the left-hand navigation pane.

After I enable the feature, AWS generates a unique issuer URL for my AWS account that hosts the OpenID Connect (OIDC) discovery endpoints at /.well-known/openid-configuration and /.well-known/jwks.json. The OpenID Connect (OIDC) discovery endpoints contain the keys and metadata necessary for token verification.

Next, I need to configure IAM permissions. My IAM principal (role or user) must have the sts:GetWebIdentityToken permission to request tokens.

For example, the following identity policy specifies access to the STS GetWebIdentityToken API, enabling the IAM principal to generate tokens.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": "sts:GetWebIdentityToken",
      "Resource": "*",
    }
  ]
}

At this stage, I need to configure the external service to trust and accept tokens issued by my AWS account. The specific steps vary by service, but generally involve:

  1. Registering my AWS account issuer URL as a trusted identity provider
  2. Configuring which claims to validate (audience, subject patterns)
  3. Mapping token claims to permissions in the external service

Let’s get started
Now, let me walk you through an example showing both the client-side token generation and server-side verification process.

First, I call the STS GetWebIdentityToken API to obtain a JWT that asserts my AWS identity. When calling the API, I can specify the intended audience, signing algorithm, and token lifetime as request parameters.

  • Audience: Populates the `aud` claim in the JWT, identifying the intended recipient of the token (for example, “my-app”)
  • DurationSeconds: The token lifetime in seconds, ranging from 60 seconds (1 minute) to 3600 seconds (1 hour), with a default of 600 seconds (5 minutes)
  • SigningAlgorithm: Choose either ES384 (ECDSA using P-384 and SHA-384) or RS256 (RSA using SHA-256)
  • Tags (optional): An array of key-value pairs that appear as custom claims in the token, which you can use to include additional context that enables external services to implement fine-grained access control

Here’s an example of getting an identity token using the AWS SDK for Python (Boto3). I can also do this using AWS Command Line Interface (AWS CLI).


import boto3

sts_client = boto3.client('sts')
response = sts_client.get_web_identity_token(
    Audience=['my-app'],
    SigningAlgorithm='ES384',  # or 'RS256'
    DurationSeconds=300
)
jwt_token = response['IdentityToken']
print(jwt_token)

This returns a signed JWT that I can inspect using any JWT parser.

{
eyJraWQiOiJFQzM4NF8wIiwidHlwIjoiSldUIiwiYWxnIjoiRVMzODQifQ.hey<REDACTED FOR BREVITY>...

I can decode the token using any JWT parser like this JWT Debugger. The token header shows it’s signed with ES384 (ECDSA).


{
  "kid": "EC384_0",
  "typ": "JWT",
  "alg": "ES384"
}

Also, the payload contains standard OIDC claims plus AWS specific metadata. The standard OIDC claims include subject (“sub”), audience (“aud”), issuer (“iss”), and others.

{
  "aud": "my-app",
  "sub": "arn:aws:iam::ACCOUNT_ID:role/MyAppRole",
  "https://sts.amazonaws.com/": {
    "aws_account": "ACCOUNT_ID",
    "source_region": "us-east-1",
    "principal_id": "arn:aws:iam::ACCOUNT_ID:role/MyAppRole"
  },
  "iss": "https://abc12345-def4-5678-90ab-cdef12345678.tokens.sts.global.api.aws",
  "exp": 1759786941,
  "iat": 1759786041,
  "jti": "5488e298-0a47-4c5b-80d7-6b4ab8a4cede"
}

AWS STS also enriches the token with identity-specific claims (such as account ID, organization ID, and principal tags) and session context. These claims provide information about the compute environment and session where the token request originated. AWS STS automatically includes these claims when applicable based on the requesting principal’s session context. You can also add custom claims to the token by passing request tags to the API call. To learn more about claims provided in the JWT, visit the documentation page.

Note the iss (issuer) claim. This is your account-specific issuer URL that external services use to verify that the token originated from a trusted AWS account. External services can verify the JWT by validating its signature using AWS’s verification keys available at a public JSON Web Key Set (JWKS) endpoint hosted at the /.well-known/jwks.json endpoint of the issuer URL.

Now, let’s look at how external services handle this identity token.

Here’s a snippet of Python example that external services can use to verify AWS tokens:


import json
import jwt
import requests
from jwt import PyJWKClient

# Trusted issuers list - obtained from EnableOutboundFederation API response
TRUSTED_ISSUERS = [
    "https://EXAMPLE.tokens.sts.global.api.aws",
    # Add your trusted AWS account issuer URLs here
    # Obtained from EnableOutboundFederation API response
]

def verify_aws_jwt(token, expected_audience=None):
    """Verify an AWS IAM outbound identity federation JWT"""
    try:
        # Get issuer from token
        unverified_payload = jwt.decode(token, options={"verify_signature": False})
        issuer = unverified_payload.get('iss')

 	# Verify issuer is trusted
        if not TRUSTED_ISSUERS or issuer not in TRUSTED_ISSUERS:
            raise ValueError(f"Untrusted issuer: {issuer}")

        # Fetch JWKS from AWS using PyJWKClient
        jwks_client = PyJWKClient(f"{issuer}/.well-known/jwks.json")
        signing_key = jwks_client.get_signing_key_from_jwt(token)

        # Verify token signature and claims
        decoded_token = jwt.decode(
            token,
            signing_key.key,
            algorithms=["ES384", "RS256"],
            audience=expected_audience,
            issuer=issuer
        )
        return decoded_token
    except Exception as e:
        print(f"Token verification failed: {e}")
        return None

Using IAM policies to control access to token generation
An IAM principal (such as a role or user) must have the sts:GetWebIdentityToken permission in their IAM policies to request tokens for authentication with external services. AWS account administrators can configure this permission in all relevant AWS policy types such as identity policies, service control policies (SCPs), resource control policies (RCPs), and virtual private cloud endpoint (VPCE) policies to control which IAM principals in their account can generate tokens.

Additionally, administrators can use the new condition keys to specify signing algorithms (sts:SigningAlgorithm), permitted token audiences (sts:IdentityTokenAudience), and maximum token lifetimes (sts:DurationSeconds). To learn more about the condition keys, visit IAM and STS Condition keys documentation page.

Additional things to know
Here are key details about this launch:

Get started with AWS IAM outbound identity federation by visiting AWS IAM console and enabling the feature in your AWS account. For more information, visit Federating AWS Identities to External Services documentation page.

Happy building!
— Donnie

Simplified developer access to AWS with ‘aws login’

Post Syndicated from Shreya Jain original https://aws.amazon.com/blogs/security/simplified-developer-access-to-aws-with-aws-login/

Getting credentials for local development with AWS is now simpler and more secure. A new AWS Command Line Interface (AWS CLI) command, aws login, lets you start building immediately after signing up for AWS without creating and managing long-term access keys. You use the same sign-in method you already use for the AWS Management Console.

In this blog, we’ll show you how to get temporary credentials to your workstation for use with the AWS CLI, AWS Software Development Kits (AWS SDKs), and tools or applications built using them with the new aws login command.

Getting started with programmatic access to AWS

You can use the aws login command with your AWS Management Console sign-in method, as described in the following sections.

Scenario 1: Using IAM credentials (root or IAM user)

To obtain programmatic credentials using your root or IAM user username and password:

  1. Install the latest AWS CLI (version 2.32.0 or later).
  2. Run the aws login command.
  3. If you have not set a default Region, the CLI prompts you to specify the AWS Region of your choice (e.g., us-east-2, eu-central-1). The CLI remembers which Region you set once you enter it into this prompt.
    Figure 1: CLI Region prompt

    Figure 1: CLI Region prompt

  4. The CLI opens your default browser.
  5. Follow the instructions in the browser window:
    1. If you have already signed into the AWS Management Console, you will see a screen that says, “Continue with an active session.”
      Figure 2: Sign in to AWS - active session selection

      Figure 2: Sign in to AWS – active session selection

    2. If you haven’t signed into the AWS Management Console, you will see the sign-in options page. Select “Continue with Root or IAM user” and log in to your AWS account.
      Figure 3: AWS Sign in to AWS - Sign-in options

      Figure 3: AWS Sign in to AWS – Sign-in options

  6. Success! You’re ready to run AWS CLI commands. Try the aws sts get-caller-identity command to verify the identity you’re currently using.
    Figure 4: Sign in to AWS - completion

    Figure 4: Sign in to AWS – completion

Scenario 2: Using federated sign-in

This scenario applies when you authenticate through your organization’s identity provider. To retrieve programmatic credentials for roles you assumed with federation:

  1. Complete steps 1–4 from Scenario 1, then continue with the following instructions.
  2. Follow the instructions in the browser window:
    1. If you have already signed into the AWS Management Console, the browser provides you with the option to select your active IAM role session from federated sign-in to the console. This enables you to switch between 5 active AWS sessions if you have multi-session support enabled on your AWS Management Console.
      Figure 5: Sign in to AWS - active IAM role session selection

      Figure 5: Sign in to AWS – active IAM role session selection

    2. If you have not signed into the AWS Management Console or want to get temporary credentials for a different IAM role, sign into your AWS account using your current authentication mechanism in another browser tab. Upon successful login, switch back to this tab and select the “Refresh” button. Your console session should now be available under the active sessions.
  3. Return to the AWS CLI once you have successfully completed the aws login process.

Regardless of the console sign-in method you choose, the temporary credentials issued by the aws login command are automatically rotated by the AWS CLI, AWS Tools for PowerShell and AWS SDKs every 15 minutes. They are valid up to the set session duration of the IAM principal (maximum of 12 hours). After reaching the session duration limit, you will be prompted to log in again.

Figure 6: AWS Sign in - session expiration

Figure 6: AWS Sign in – session expiration

Accessing AWS using local developer tools

The aws login command supports switching between multiple AWS accounts and roles using profiles. You can configure a profile with aws login --profile <PROFILE_NAME> and run AWS commands with the profile using: aws sts get-caller-identity --profile <PROFILE_NAME>. The short-term credentials issued by aws login work with more than the AWS CLI. You can also use them with:

  • AWS SDKs: If you use AWS SDKs for development, the SDK clients can use these temporary credentials to authenticate with AWS.
  • AWS Tools for PowerShell: Use the Invoke-AWSLogin command.
  • Remote development servers: Use aws login --remote on a remote server without browser access, to deliver temporary credentials from your device with browser access to the AWS console.
  • Older versions of AWS SDKs that do not support the new console credentials provider: Any software written using these older SDKs can support credentials delivered by aws login by using the credential_process provider with the AWS CLI.

Controlling access to aws login with IAM policies

The aws login command is controlled by two IAM actions: signin:AuthorizeOAuth2Access and signin:CreateOAuth2Token. Use the SignInLocalDevelopmentAccess managed policy or add these actions to your IAM policies to allow IAM users and IAM roles with console access to use this feature.

AWS Organizations customers looking to control the usage of this login feature on member accounts can deny the two actions above using Service Control Policies (SCPs). These IAM actions and their resources are usable in all relevant IAM policies.

AWS recommends using centralized root access management in AWS Organizations to eliminate long-term root credentials from member accounts. This feature allows security teams to perform privileged tasks through short-term, task-scoped root sessions from a central management account. After you enable centralized root management and delete root credentials on member accounts, root login to member accounts is denied, which also prevents programmatic access with root credentials using aws login. For developers using root credentials or IAM users, aws login delivers short-lived credentials to development tools, providing a secure alternative to long-term static access keys.

Logging and security of programmatic access using aws login

AWS Sign-In logs API activity through AWS CloudTrail, which now includes two new events specific to aws login. The service logs two new event names called AuthorizeOAuth2Access and CreateOauth2Token in the AWS Region where the user logs in.

Here’s a CloudTrail sample for an AuthorizeOAuth2Access event:

{
    "eventVersion": "1.11",
    "userIdentity": {
        "type": "AssumedRole",
        "principalId": "AROATJHQDX737YZP72NTF:testuser”,
        "arn": "arn:aws:sts::225989345271:assumed-role/Admin/testuser,
        "accountId": “111111111111”,
        "sessionContext": {
            "sessionIssuer": {
                "type": "Role",
                "principalId": "AROATJHQDX737YZP72NTF",
                "arn": "arn:aws:iam::111111111111:role/Admin",
                "accountId": “11111111111”,
                "userName": "Admin"
            },
            "attributes": {
                "creationDate": "2025-11-17T22:50:14Z",
                "mfaAuthenticated": "false"
            }
        }
    },
    "eventTime": "2025-11-17T22:51:32Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "AuthorizeOAuth2Access",
    "awsRegion": "us-east-1",
    "sourceIPAddress": “192.0.2.2”,
    "userAgent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/142.0.0.0 Safari/537.36",
    "requestParameters": {
        "scope": "openid",
        "redirect_uri": "http://127.0.0.1:53037/oauth/callback",
        "code_challenge_method": "SHA-256",
        "client_id": "arn:aws:signin:::devtools/same-device"
    },
    "responseElements": null,
    "additionalEventData": {
        "success": "true",
        "x-amzn-vpce-id": ""
    },
    "requestID": "e2854c76-1cba-4360-9fd1-5037b591466b",
    "eventID": "59e1720d-3deb-44ff-933d-6828be2a860a",
    "readOnly": true,
    "eventType": "AwsApiCall",
    "managementEvent": true,
    "recipientAccountId": “111111111111”,
    "eventCategory": "Management",
    "tlsDetails": {
        "tlsVersion": "TLSv1.3",
        "cipherSuite": "TLS_AES_128_GCM_SHA256",
        "clientProvidedHostHeader": "us-east-1.signin.aws.amazon.com"
    }
}

Here’s a CloudTrail sample for a CreateOAuth2Token event:

{
    "eventVersion": "1.11",
    "userIdentity": {
        "type": "AssumedRole",
        "principalId": "AROATJHQDX737YZP72NTF:testuser-Isengard",
        "arn": "arn:aws:sts::111111111111:assumed-role/Admin/testuser-Isengard",
        "accountId": "111111111111",
        "sessionContext": {
            "sessionIssuer": {
                "type": "Role",
                "principalId": "AROATJHQDX737YZP72NTF",
                "arn": "arn:aws:iam::111111111111:role/Admin",
                "accountId": "111111111111",
                "userName": "Admin"
            },
            "attributes": {
                "creationDate": "2025-11-18T20:38:10Z",
                "mfaAuthenticated": "false"
            }
        }
    },
    "eventTime": "2025-11-18T20:38:44Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "CreateOAuth2Token",
    "awsRegion": "us-east-1",
    "sourceIPAddress": "192.0.2.2",
    "userAgent": "aws-cli/2.32.0 md/awscrt#0.28.4 ua/2.1 os/macos#24.6.0 md/arch#arm64 lang/python#3.13.9 md/pyimpl#CPython m/b,AA,Z,E cfg/retry-mode#standard md/installer#exe sid/35033f4ca1bd md/prompt#off md/command#login",
    "requestParameters": {
        "client_id": "arn:aws:signin:::devtools/same-device"
    },
    "responseElements": null,
    "additionalEventData": {
        "success": "true",
        "x-amzn-vpce-id": ""
    },
    "requestID": "94562943-c85b-4dc1-bf72-43b0fd42d6de",
    "eventID": "0b338fac-6a10-4740-b34d-1bb6923e799e",
    "readOnly": true,
    "eventType": "AwsApiCall",
    "managementEvent": true,
    "recipientAccountId": "111111111111",
    "eventCategory": "Management",
    "tlsDetails": {
        "tlsVersion": "TLSv1.3",
        "cipherSuite": "TLS_AES_128_GCM_SHA256",
        "clientProvidedHostHeader": "us-east-1.signin.aws.amazon.com"
    }
}

The aws login command uses the OAuth 2.0 authorization code flow with PKCE (Proof Key for Code Exchange) to protect against authorization code interception attacks. This provides a secure alternative to setting up IAM user access keys for getting started with development on AWS. For guidance on additional modern authentication approaches and alternatives to long-term IAM access keys, see the AWS Security Blog post “Beyond IAM access keys: Modern authentication approaches for AWS.”

Conclusion

The login for AWS local development feature is a secure-by-default enhancement that helps customers eliminate the use of long-term credentials for programmatic access with AWS. With aws login, you can start building immediately using the same credentials you use to sign in to the AWS Management Console. This feature is now available across all AWS commercial Regions (excluding China and GovCloud) at no additional cost to customers.

For more information, visit the authentication and access section in the CLI user guide.

If you have feedback about this post, submit comments in the Comments section below.

Shreya Jain

Shreya Jain

Shreya is a Senior Technical Product Manager in AWS Identity. She is energized by bringing clarity and simplicity to complex ideas. When she’s not applying her creative energy at work, you’ll find her at Pilates, dancing, or discovering her next favorite coffee shop.

Sowjanya Rajavaram

Sowjanya Rajavaram

Sowjanya is a Sr Solutions Architect who specializes in Identity and Security in AWS. She works on helping customers of all sizes solve their identity and access management problems. She enjoys traveling and exploring new cultures and food.

AWS designated as a critical third-party provider under EU’s DORA regulation

Post Syndicated from Andrew Vennekotter original https://aws.amazon.com/blogs/security/aws-designated-as-a-critical-third-party-provider-under-eus-dora-regulation/

Amazon Web Services has been designated as a critical third-party provider (CTPP) by the European Supervisory Authorities (ESAs) under the European Union’s Digital Operational Resilience Act (DORA).

This designation is a key milestone in the EU’s implementation of DORA, which took effect in January 2025 and aims to strengthen the operational resilience of the EU financial sector. Under this regulation, certain third-party information and communications technology (ICT) service providers identified as playing a critical role for financial entities in the EU are subject to direct joint oversight by the European Banking Authority (EBA), the European Securities and Markets Authority (ESMA), and the European Insurance and Occupational Pensions Authority (EIOPA).

AWS recognizes the significance of this oversight for our financial services customers as they advance their digital transformation and modernization efforts, which remain essential to their long-term resilience and competitiveness.

What the CTPP designation means for customers

  • Financial institutions that use AWS services should note that AWS is engaged in an active oversight relationship with the ESAs.
  • AWS will maintain its commitment to operational resilience as part of the oversight activities associated with the designation.
  • Customers can use AWS security, resilience, and compliance features while maintaining control over their own cloud environments and compliance journeys.

Proven readiness for DORA oversight

AWS has been engaging with EU institutions, national competent authorities, and the broader financial regulatory community for years, helping to build a more resilient and secure financial system.

Our readiness for this oversight process builds on our demonstrated experience in meeting rigorous operational and regulatory standards. AWS has made, and will continue to make, investments in compliance, risk management, operational resilience, and transparency, which are critical pillars of DORA.

Being designated as a CTPP means AWS will now participate in a formal oversight process. We expect that this process will promote a deeper understanding of how AWS and other cloud technologies help enhance the resilience of the financial services industry.

Supporting customers through DORA implementation

Although AWS is now subject to direct oversight under DORA, we remain equally focused on supporting our financial services customers that are subject to the regulation.

Operational resilience is both a compliance requirement for DORA and a business necessity. Our services are designed to help financial institutions achieve high availability, durability, and scalability, while maintaining robust controls and visibility into their operations.

Our dedicated team of security and compliance specialists is ready to assist financial organizations in understanding how AWS security and compliance features can help them fulfill their obligations under DORA and how AWS services help to support their compliance strategies. We offer detailed documentation, whitepapers, and compliance guides tailored to DORA’s key requirements, such as the AWS User Guide to DORA and Amazon Web Services’ Approach to Operational Resilience in the Financial Sector & Beyond. To learn more about our security and compliance resources, visit the AWS Trust Center. Customers can also download our third-party attestations and certifications through AWS Artifact.

If you have feedback about this post, submit comments in the Comments section below.

Andrew Vennekotter

Andrew Vennekotter

Andrew is the Head of Regulatory Assurance for EMEA within the AWS Security organization. He combines 16 years of public sector experience in technology policy, cybersecurity, counterterrorism, and security policy at NASA and the U.S. State Department with nine years of experience in software engineering, information security, and responsible AI. In his spare time, he enjoys hiking, coming up with new dad jokes, and pretending to be a novelist.
Simplify cloud security with managed rules from AWS Marketplace for AWS Network Firewall

Post Syndicated from Dhanil Parwani original https://aws.amazon.com/blogs/security/simplify-cloud-security-with-managed-rules-from-aws-marketplace-for-aws-network-firewall/

AWS Network Firewall now supports managed rules curated by AWS Partners—giving you pre-built threat intelligence and security controls that reduce the need to create and maintain your own rule sets. This new capability helps organizations strengthen their network security posture with continuously updated AWS partner managed protection.

What are managed rules from AWS Marketplace for Network Firewall?

Managed rules from AWS Marketplace are curated by AWS Partners who automatically update rules to address emerging threats, providing you comprehensive protection without the operational overhead of managing custom rules. As shown in Figure 1, you can now deploy Network Firewall managed rules from AWS Marketplace in a few clicks, reducing the time it takes you to create custom security rules. You can use the AWS Management Console to choose from a variety of specialized rule groups tailored to different industry needs, compliance requirements, and threat landscapes.

Figure 1: Adding managed rules from AWS Marketplace for AWS Network Firewall

Figure 1: Managed rules from AWS Marketplace for AWS Network Firewall

Key benefits and use cases

Managing firewalls across multiple virtual private clouds (VPCs) can become challenging when it comes to keeping up with creating, maintaining, and updating custom rule sets. This only increases with the growing number of firewalls that require constant monitoring to protect against emerging threats and new attack vectors. While AWS Managed Rules rule groups provide a solid foundation, managed rules from AWS Marketplace help customers add expert-curated rules with a few clicks.

You can associate managed rules from AWS Marketplace partners directly to your AWS Network Firewall and see them in action in one of the many network firewall deployment models as shown in Deployment models for AWS Network Firewall with VPC routing enhancements. These rules seamlessly fit into your traffic inspection patterns and don’t require additional routing-related configuration changes.

Keeping up to date on the constantly changing threat landscape can be time-consuming and expensive. AWS Marketplace partners automatically update managed rule groups and provide new versions of rule groups when new vulnerabilities and threats emerge. Continuously updated rules lead to a more robust security posture.

Prerequisites

To start using managed rules from AWS Marketplace, you need to meet the following prerequisites:

You can use managed rules from AWS Marketplace partners with all Network Firewall deployment models.

Set up AWS Marketplace managed rules

With the prerequisites in place, you’re ready to set up managed rules from AWS Marketplace.

To set up managed rules:

  1. Sign in to the Amazon Virtual Private Cloud (Amazon VPC) console.
  2. In the navigation pane, choose Network Firewall and then choose Network Firewall rule groups.
  3. Choose AWS Marketplace.

    Figure 2: AWS Marketplace rule groups

    Figure 2: AWS Marketplace rule groups

  4. Under AWS Marketplace, you’ll see different types of rule groups curated by AWS Partners. You can select the partner and the rule group you want to apply as part of your Network Firewall policies. Locate the partner and rule group that you want to add and choose View subscription options next to that rule group.

    Figure 3: View subscription options for partner rule groups in AWS Marketplace

    Figure 3: View subscription options for partner rule groups in AWS Marketplace

  5. After you choose View subscription options, you’ll see the Subscription options window. Review the options and then choose Subscribe.

    Figure 4: Review subscription options and subscribe to partner product

    Figure 4: Review subscription options and subscribe to partner product

  6. When subscribed, go to Firewall Policies and choose from an existing firewall policy or create a new one as described in Creating a firewall policy.

    Figure 5: Choose a firewall policy to associate rule groups

    Figure 5: Choose a firewall policy to associate rule groups

  7. After you select the firewall policy, choose Actions and then select Add Partner managed rule groups.
    Figure 6: Add partner managed rule groups

    Figure 6: Add partner managed rule groups

  8. After you choose Add partner managed rule groups, select the previously subscribed rule groups.
    Figure 7: Select the rule groups

    Figure 7: Select the rule groups

  9. Choose Add to policy and confirm the rule groups were added to your firewall policy. You can modify rule groups later if necessary.

The firewall policy with partner managed rule groups is now ready to be associated to your Network Firewall as noted in Step 7 of Create a firewall.

Launch partners

We had the pleasure to work with the following partners at the launch of managed rules from AWS Marketplace for Network Firewall. Here is what some of our partners (in alphabetical order) have been saying. We continue to work with our partners to create more managed rule groups over time, which you can follow at AWS Network Firewall Partners.

Check Point Software

From pioneering stateful firewalls to our AI-powered, cloud-delivered security solutions, Check Point Software is committed to safeguarding organizations with an industry-leading 99.9% prevention rate. Check Point Managed Rules for AWS Network Firewall simplifies security by providing pre-configured rule sets designed by Check Point ThreatCloud AI experts. Delivered directly through AWS Marketplace, these rules enhance protection against hundreds of Common Vulnerabilities and Exposures (CVEs) and OWASP Top 10 vulnerabilities reducing manual effort and strengthening your cloud security posture.

Fortinet

Fortinet, a global leader in cybersecurity and trusted name in next-generation firewalls, now brings its AI-driven threat intelligence to AWS Network Firewall. The new Fortinet Managed IPS Rules deliver continuously updated, automated protection against exploits, malware, and command-and-control threats—enhancing AWS security without added complexity.

Infoblox

Infoblox unites networking, security and cloud with a protective DDI platform that delivers enterprise resilience and agility. Trusted by more than 13,000 customers, including the majority of Fortune 100 companies as well as emerging innovators, we seamlessly integrate, secure and automate critical network services so businesses can move fast without compromise.

Lumen

Lumen is thrilled to launch Defender Managed Rules for AWS Network Firewall, available now on AWS Marketplace. In partnership with AWS, this managed rule group brings proactive Black Lotus Labs-powered threat intelligence directly into AWS environments—enabling organizations to automatically block risky IPs using real-time, backbone-level data from Lumen’s global network. With seamless AWS Management Console integration and automatic updates, security and network teams can strengthen cloud defenses with expert-curated protection—no manual rule writing needed.

Rapid7

Rapid7 Managed Rules for AWS Network Firewall converts our curated, high-fidelity threat intelligence into dynamic, self-cleaning rule groups, delivering expert-vetted protection directly into your native AWS environment. Instantly deploy current protections against today’s most pressing threats, allowing your team to act with confidence and significantly reduce alert fatigue.

ThreatSTOP

ThreatSTOP delivers continuously updated threat intelligence that automatically blocks malicious domains and IPs through AWS Network Firewall. Building on its proven protection for AWS WAF, ThreatSTOP extends the same trusted enforcement to the network layer to protect both inbound and outbound traffic. The managed rules leverage thousands of curated global sources and proprietary research from the ThreatSTOP Security, Intelligence, and Research team to block command-and-control, phishing, and malware traffic in real time. Available in AWS Marketplace, ThreatSTOP helps organizations strengthen their cloud security posture, reduce unwanted connections, and maintain compliance with ITAR and OFAC requirements.

Trend Micro

Trend Micro, a leader in cloud-native application protection platforms (CNAPP), brings deep expertise in securing cloud environments to AWS customers. Backed by Trend Zero Day Initiative (ZDI), Trend Micro delivers curated, continuously updated malware rule groups, with CVE and exploit protection coming soon. Using early threat intelligence from ZDI, protections are published faster than other vendors, helping AWS customers stay ahead of attackers.

Partner statements represent their own views and claims. AWS does not independently verify partner performance metrics.

Conclusion

With managed rules from AWS Marketplace, customers can find, buy, and deploy industry-leading threat intelligence directly from the AWS Network Firewall console. By using these pre-built rules, security teams can focus on strategic initiatives while maintaining strong network protection. Evaluate available partner offerings and select rules that align with your security requirements and compliance needs.

Visit the AWS Network Firewall Documentation to learn more about implementing partner managed rules for your organization.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS Network Firewall re:Post or contact AWS Support.

Dhanil Parwani
Dhanil Parwani

Dhanil is a Senior Partner Solutions Architect at AWS. He works closely with networking, security, and AI partners to build solutions and capabilities to enable and simplify their migrations and operations in the cloud. He holds an MS in telecommunications from the University of Colorado Boulder and has a passion for computer networking. Outside of work, Dhanil is an avid traveler and enjoys cheering on Liverpool, FC.
Amish Shah
Amish Shah

Amish is a seasoned product leader with more than 15 years of experience developing innovative and scalable solutions for networking, security, and cloud use cases. He currently leads the AWS Network Firewall service, where he helps develop security solutions that protect AWS workloads. Outside of work, Amish enjoys playing cricket and soccer, loves to travel, and has recently started collecting niche fragrances..

New Amazon Threat Intelligence findings: Nation-state actors bridging cyber and kinetic warfare

Post Syndicated from CJ Moses original https://aws.amazon.com/blogs/security/new-amazon-threat-intelligence-findings-nation-state-actors-bridging-cyber-and-kinetic-warfare/

The new threat landscape

The line between cyber warfare and traditional kinetic operations is rapidly blurring. Recent investigations by Amazon threat intelligence teams have uncovered a new trend that they’re calling cyber-enabled kinetic targeting in which nation-state threat actors systematically use cyber operations to enable and enhance physical operations. Traditional cybersecurity frameworks often treat digital and physical threats as separate domains. However, research by Amazon demonstrates that this separation is increasingly artificial. Multiple nation-state threat groups are pioneering a new operational model where cyber reconnaissance directly enables kinetic targeting.

We’re seeing a fundamental shift in how nation-state actors approach warfare. These aren’t just cyber attacks that happen to cause physical damage; they are coordinated campaigns where digital operations are specifically designed to support physical military objectives.

Unique visibility at Amazon

The ability of Amazon Threat Intelligence to identify these campaigns stems from their unique position in the global threat landscape:

  • Threat intelligence telemetry: Amazon global cloud operations provide visibility into threats across diverse environments, including intelligence from Amazon MadPot honeypot systems, which enable the detection of suspicious patterns, actor infrastructure, and the network pathways used in these cyber-enabled kinetic targeting campaigns.
  • Opt-in customer data: Real-world data about attempted threat actor activities provided on an opt-in basis from enterprise environments.
  • Industry partner collaboration: Threat intelligence sharing with leading security organizations and government agencies provides additional context and validation for observed activities.

Through this multi-source approach, Amazon can connect dots that might otherwise remain invisible to individual organizations or even government agencies operating in isolation.

Case study 1: Imperial Kitten’s maritime campaign

The first case study involves Imperial Kitten, a threat group suspected of operating on behalf of Iran’s Islamic Revolutionary Guard Corps (IRGC). The timeline reveals the progression from digital reconnaissance to physical attack:

  • December 4, 2021: Imperial Kitten compromises a maritime vessel’s Automatic Identification System (AIS) platform, gaining access to critical shipping infrastructure. The Amazon Threat Intelligence team identifies the compromise and works with the affected organization to remediate the security event.
  • August 14, 2022: The threat actor expands their maritime targeting of additional vessel platforms. In one incident, they gained access to CCTV cameras aboard a maritime vessel, which provided real-time visual intelligence.
  • January 27, 2024: Imperial Kitten conducts targeted searches for AIS location data for a specific shipping vessel. This represents a clear shift from broad reconnaissance to targeted intelligence gathering.
  • February 1, 2024: US Central Command reports a missile strike by Houthi forces against the exact vessel that Imperial Kitten had been tracking. While the missile strike was ultimately ineffective, the correlation between the cyber reconnaissance and kinetic strike is unmistakable.

This case demonstrates how cyber operations can provide adversaries with the precise intelligence needed to conduct targeted physical attacks against maritime infrastructure—a critical component of global commerce and military logistics.

Case study 2: MuddyWater’s Jerusalem operations

The second case study involves MuddyWater, a threat group attributed by the US government to Rana Intelligence Computer Company, operating at the behest of Iran’s Ministry of Intelligence and Security (MOIS). This case reveals an even more direct connection between cyber operations and kinetic targeting.

  • May 13, 2025: MuddyWater provisions a server specifically for cyber network operations, establishing the infrastructure needed for their campaign.
  • June 17, 2025: The threat actor uses their server infrastructure to access another compromised server containing live CCTV streams from Jerusalem. This provides real-time visual intelligence of potential targets within the city.
  • June 23, 2025: Iran launches widespread missile attacks against Jerusalem. On the same day, Israeli authorities report that Iranian forces were exploiting compromised security cameras to gather real-time intelligence and adjust missile targeting.

The timing is not coincidental. As reported by The Record, Israeli officials urged citizens to disconnect internet-connected security cameras, warning that Iran was exploiting them to “gather real-time intelligence and adjust missile targeting.”

Technical infrastructure and methods

Research by Amazon reveals the sophisticated technical infrastructure supporting these operations. The threat actors employ a multi-layered approach:

  1. Anonymizing VPN networks: Threat actors route their traffic through anonymizing VPN services to obscure their true origins and make attribution more difficult.
  2. Actor-controlled servers: Dedicated infrastructure provides persistent access and command-and-control capabilities for ongoing operations.
  3. Compromised enterprise systems: The ultimate targets—enterprise servers hosting critical infrastructure like CCTV systems, maritime platforms, and other intelligence-rich environments.
  4. Real-time data streaming: Live feeds from compromised cameras and sensors provide actionable intelligence that can be used to adjust targeting in near real time.

Defining a new category of warfare

The research team proposes new terminology to describe these hybrid operations. Traditional frameworks fall short:

  • Cyber-kinetic operations typically refer to cyber attacks that cause physical damage to systems
  • Hybrid warfare is too broad, encompassing multiple types of warfare without specific focus on the cyber-physical integration

Amazon researchers suggest cyber-enabled kinetic targeting as a more precise term for campaigns where cyber operations are specifically designed to enable and enhance kinetic military operations.

Implications for defenders

For the cybersecurity community, this research serves as both a warning and a call to action. Defenders must adapt their strategies to address threats that span both digital and physical domains. Organizations that historically believed they weren’t of interest to threat actors could now be targeted for tactical intelligence. We must expand our threat models, enhance our intelligence sharing, and develop new defensive strategies that account for the reality of cyber-enabled kinetic targeting across diverse adversaries.

  • Expanded threat modeling: Organizations must consider not just the direct impact of cyberattacks, but how compromised systems might be used to support physical attacks against themselves or others.
  • Critical infrastructure protection: Operators of maritime systems, urban surveillance networks, and other infrastructure must recognize that their systems might be valuable not just for espionage, but as targeting aids for kinetic operations.
  • Intelligence sharing: The cases demonstrate the critical importance of threat intelligence sharing between private sector organizations, government agencies, and international partners.
  • Attribution challenges: When cyber operations directly enable kinetic attacks, the attribution and response frameworks become more complex, potentially requiring coordination between cybersecurity, military, and diplomatic channels.

Looking forward

We believe that cyber-enabled kinetic targeting will become increasingly common across multiple adversaries. Nation-state actors are recognizing the force multiplier effect of combining digital reconnaissance with physical attacks. This trend represents a fundamental evolution in warfare, where the traditional boundaries between cyber and kinetic operations are dissolving.

Indicators of Compromise

IOC Value, IOC Type, First Seen, Last Seen, Annotation
18[.]219.14.54, IPv4, 2025-05-13, 2025-06-17, MuddyWater Command and Control IP address
85[.]239.63.179, IPv4, 2023-08-13, 2025-09-19, Imperial Kitten proxy IP address
37[.]120.233.84, IPv4, 2021-01-01, 2022-11-01, Imperial Kitten proxy IP address
95[.]179.207.105, IPv4, 2020-11-11, 2022-04-09, Imperial Kitten proxy IP address

This blog post is based on research presented at CYBERWARCON by David Magnotti, Principal Engineer, and Dlshad Othman, Senior Threat Intelligence Engineer, both of Amazon Threat Intelligence. The authors thank US Central Command for their transparency in reporting military activities and acknowledge the ongoing support of customers and partners in these critical investigations.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

CJ Moses

CJ Moses

CJ Moses is the CISO of Amazon Integrated Security. In his role, CJ leads security engineering and operations across Amazon. His mission is to enable Amazon businesses by making the benefits of security the path of least resistance. CJ joined Amazon in December 2007, holding various roles including Consumer CISO, and most recently AWS CISO, before becoming CISO of Amazon Integrated Security September of 2023.

Prior to joining Amazon, CJ led the technical analysis of computer and network intrusion efforts at the Federal Bureau of Investigation’s Cyber Division. CJ also served as a Special Agent with the Air Force Office of Special Investigations (AFOSI). CJ led several computer intrusion investigations seen as foundational to the security industry today.

CJ holds degrees in Computer Science and Criminal Justice, and is an active SRO GT America GT2 race car driver.

Analyze AWS Network Firewall logs using Amazon OpenSearch dashboard

Post Syndicated from Hoorang Broujerdi original https://aws.amazon.com/blogs/security/analyze-aws-network-firewall-logs-using-amazon-opensearch-dashboard/

Amazon CloudWatch and Amazon OpenSearch Service have launched a new dashboard that simplifies the analysis of AWS Network Firewall logs. Previously, in our blog post How to analyze AWS Network Firewall logs using Amazon OpenSearch Service we demonstrated the required services and steps to create an OpenSearch dashboard. The new dashboard removes these extra steps and streamlines the entire process. In this post, I show you how to build and use the new OpenSearch Service dashboards to analyze Network Firewall logs more efficiently.

Network Firewall is a managed security service that protects Amazon Virtual Private Cloud (Amazon VPC) VPCs by monitoring and filtering network traffic. Network Firewall provides stateful inspection, which gives you information that you can use to create custom rules to control incoming and outgoing traffic. It automatically scales, offers high availability, and integrates with other AWS security services, in addition to helping to block unexpected traffic, prevent unauthorized access, and filter traffic based on domains and IP addresses.

Analyzing Network Firewall logs provides you with insight into the traffic entering or leaving your VPC and helps you troubleshoot issues and understand your security posture over time. This analysis is crucial for maintaining effective security controls.

Network Firewall generates three types of logs from its stateful engine:

  • Flow logs: These capture standard network traffic flow information based on your stateless rules
  • Alert logs: These show traffic that matches stateful rules configured with DROP, ALERT, or REJECT actions
  • TLS logs: These provide details about TLS inspection events (requires TLS inspection configuration)

Prerequisites

This post assumes that you’re familiar with the fundamentals of AWS networking concepts and services such as Amazon VPC, subnets, routing tables, and other services such as Network Firewall, Amazon CloudWatch, and OpenSearch Service.

To analyze Network Firewall logs using OpenSearch Service, you must have:

  1. An active Network Firewall in your VPC
  2. CloudWatch log groups configured for:
    1. Flow logs, for example /inspection-nwfw-flow-logs
    2. Alert logs, for example /inspection-nwfw-alert-logs

If you haven’t deployed Network Firewall in your VPC, you can use one of the available Network Firewall deployment architecture templates to create a firewall. After creating a firewall, configure CloudWatch log groups for the firewall flow and alert logs and configure stateful logging. Fine-tune your firewall policy and rule configuration and make sure that you’re routing traffic symmetrically through the firewall. Verify that your CloudWatch log groups are receiving firewall logs. You can do this by navigating to the AWS Management Console for CloudWatch, selecting your log group, and viewing the log streams under the Log streams tab.

With the firewall in the routed path and publishing metrics and log events, you can proceed with creating a Network Firewall OpenSearch dashboard.

Scenario

In this post, I show you how to set up a centralized architecture, single Availability Zone deployment as shown in Figure 1. Then, you will create an OpenSearch dashboard for your firewall to monitor and analyze traffic.

Figure 1: Network Firewall centralized architecture, single Availability Zone deployment

Solution deployment

To analyze Network Firewall logs in OpenSearch Service, you first need to create an OpenSearch integration.

To create an OpenSearch Service integration:

  1. Open the Amazon CloudWatch console.
  2. Choose Settings in the navigation pane.
  3. Choose the Logs tab.
  4. Scroll down to find OpenSearch integration and choose Create integration.

Figure 2: Create an OpenSearch integration

  1. There are three items to be configured under OpenSearch collection:
    1. Enter a name for Integration name. For example, CW-AOS-Integration01.
    2. KMS key ARN – optional is optional. If you leave that empty, your data will be encrypted by default with a key that AWS owns and manages. You also have an option to create and use an AWS Key Management Service (AWS KMS) key.
    3. For Data retention, select a number between 1 and 30 depending on your retention policy. For example, select 10 to retain logs for 10 days.

Figure 3: Configure an OpenSearch collection

  1. Next, you need to configure AWS Identity and Access Management (IAM) permissions.
    1. For the IAM role for writing to OpenSearch collection, you can either create a new role or use an existing role. If you choose Create new role, then you need to provide an IAM role name. For example, CWLogQueryOS. This role must have permissions to read from all log groups in the account. See Permissions that the integration needs for an example of the permission that the integration needs.
    2. IAM roles and users who can view dashboards defines who can view the dashboards. Select either:
      • Allow all roles and users in this account to view dashboards.
      • Specify roles and users who can view dashboards. By choosing Specify roles…, you can select the IAM roles and users who can view the dashboard.
    3. Choose Confirm integration setup to create the integration. It might take 1–5 minutes for the integration to be created.

Figure 4: Configure IAM permissions

After you receive notification of successful creation of the OpenSearch integration, you can create an OpenSearch dashboard.

To create an OpenSearch dashboard:

  1. Navigate to Amazon CloudWatch console and choose Logs insights in the navigation pane.
  2. In Logs Insights, choose the Analyze with OpenSearch tab.
  3. Choose Create dashboard.
  4. Under Select dashboard type, select AWS Network Firewall.
  5. Enter a name for the dashboard, such as InspectionFirewall.

Figure 5: Select the dashboard type and enter a name

  1. Under Dashboard data configuration, select Every 5 minutes.
  2. Under Select log groups, select Inspection-nwfw-alert-logs and Inspection-nwfw-flow-logs.

Figure 6: Select data synchronization frequency and log groups

  1. Choose Create dashboard. If you have multiple firewalls in your environment, repeat steps 1–8 to create a dashboard for each Firewall.
  2. Choose Select a dashboard and select and select a dashboard to view.

Figure 7: View a list of existing firewalls in OpenSearch dashboards

Dashboard overview

Your new OpenSearch dashboard, similar to Figure 8, provides you with visual insight into some of your firewall events such as:

  • Top talkers
  • Top protocols
  • Alert log analysis
  • Firewall engines

Figure 8: Network Firewall OpenSearch dashboard

As shown in Figure 9, you can refine your analysis to focus on a specific traffic pattern or security event by using the filters at the top of the dashboard to focus on traffic based on:

  • Source or destination addresses
  • Protocols
  • Actions
  • Firewall names

Figure 9: Network Firewall OpenSearch dashboard filters

To dive deep into a widget:

  • Hover your cursor over a widget in the dashboard to reveal the options menu icon (…) in the top right corner of the widget.
  • Choose the options menu icon (…) to maximize the widget or open the Inspect view, as shown in Figure 10.

Figure 10: Top Source IP by Packets widget showing the options menu icon (…)

Figure 11 shows the Inspect window for the Top Source IP by Packets widget. In this window, you can get information by selecting Statistics, Request, or Response.

Figure 11: Inspect window for Top Source IP by Packets widget

This window might look different depending on the widget you choose. Some widget options menus provide more information than others and include an option to download the information in CSV format. For example, you can use the Top Source IPs by Packets and Bytes widget to view data and download it in CSV format, as shown in Figure 12.

Figure 12: Inspect window for Top Source IPs by Packets and Bytes widget

When using the Top Source IPs by Packets and Bytes, you can use the View menu to switch the view from Data to Requests to access more information, as shown in Figure 13.

Figure 13: Switch the Inspect window view for Top Source IPs by Packets and Bytes widgets between Data and Requests

Example use cases

The following are some examples of how you can use the Network Firewall OpenSearch dashboard to facilitate monitoring and troubleshooting:

  • Identify unusual traffic patterns:
    • Use the Top Source IPs by Packets and Bytes widget
    • Look for unexpected spikes or outliers
  • Monitor security rule effectiveness:
    • Analyze the Alert Log Analysis section
    • Track which rules are triggering most frequently
  • Troubleshoot connectivity issues:
    • Use filters to isolate traffic for specific IP ranges
    • Examine flow logs for blocked connections
  • Verify compliance:
    • Review TLS logs to verify encryption standards
    • Use filters to focus on traffic to and from sensitive resources

Cost considerations

You will incur charges for AWS Network Firewall and the OpenSearch services used. For more information, see AWS Network Firewall Pricing and Amazon CloudWatch Pricing.

Conclusion

By building Amazon OpenSearch Service dashboards for AWS Network Firewall logs to transform complex security data into actionable insights, you can monitor and analyze your network security posture more effectively. By combining the robust security features of Network Firewall with the powerful visualization capabilities offered by OpenSearch Service, you gain real-time visibility into network traffic patterns, can quickly identify potential security threats, and streamline your troubleshooting workflows. This solution reduces the mean time to detect security incidents and improves operational efficiency through visual analytics to support data-driven decision making. Whether you’re focusing on threat detection, compliance monitoring, or security optimization, these dashboards can provide the visibility and insights needed to strengthen your overall security posture.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Hoorang Broujerdi

Hoorang Broujerdi

Hoorang is a Senior Technical Account Manager at AWS Enterprise Support with more than two decades of experience. He helps organizations architect resilient, secure, and efficient cloud environments, guiding them through complex networking challenges and large-scale infrastructure transformations. He has helped numerous organizations enhance their cloud operations through targeted optimizations, robust architectures, and best-practice implementations.

How to automate Session Manager preferences across your organization

Post Syndicated from Nima Fotouhi original https://aws.amazon.com/blogs/security/how-to-automate-session-manager-preferences-across-your-organization/

AWS Systems Manager Session Manager is a fully managed service that provides secure, interactive, one-click access to your Amazon Elastic Compute Cloud (Amazon EC2) instances, edge devices, and virtual machines (VMs) through a browser-based shell or AWS Command Line Interface (AWS CLI), without requiring open inbound ports, bastion hosts, or SSH keys. Session Manager helps you maintain security compliance and controlled access while providing users with access to managed nodes. When starting a session, you must specify a preferences document (known as the Session Manager preferences document) to set the session parameters.

While providing users with access to managed nodes, managing these preferences consistently across multiple AWS Regions and accounts in a large organization can be challenging. Organizations often need to maintain standardized security settings, logging configurations, and session controls across their entire AWS footprint. Manual configuration of these preferences in each Region and account is not only time-consuming but also prone to human error and can lead to security gaps or compliance violations. Additionally, tracking and maintaining these configurations becomes increasingly complex as the organization scales.

You can use Session Manager to control various session options including data encryption for session data in transit and session logs at rest, session duration, and logging. For example, you can specify whether to store session log data in an Amazon Simple Storage Service (Amazon S3) bucket or Amazon CloudWatch Logs log group. In this post, I demonstrate how to manage Session Manager preferences across your organization using AWS CloudFormation StackSets. You can use CloudFormation StackSets to manage resources and configurations, such as Session Manager preferences, across different AWS accounts and Regions using standardized templates to maintain consistent security and compliance standards across your entire AWS infrastructure.

Prerequisites

You need to meet the following prerequisites to deploy the solution in this post:

  • Basic understanding of CloudFormation
  • Trusted access enabled between CloudFormation StackSets and AWS Organizations
  • Access to an AWS management account or StackSet delegated admin account
  • Appropriate AWS Identity and Access Management (IAM) permissions to create and manage StackSets

The Session Manager environment has some additional prerequisites:

  • For EC2 instances with internet access, allow HTTPS (port 443) outbound traffic to:
    • ec2messages.<region>.amazonaws.com
    • ssm.<region>.amazonaws.com
    • ssmmessages.<region>.amazonaws.com

    Note: <region> represents the actual Region where you are deploying your instances.

  • Additional endpoints required for specific features:
    • For CloudWatch Logs integration: logs.<region>.amazonaws.com
    • For Amazon S3 log storage: s3.<region>.amazonaws.com
    • For session data encryption: kms.<region>.amazonaws.com

    Note: For EC2 instances without internet access, you must configure virtual private cloud (VPC) endpoints to maintain connectivity with Systems Manager and related services.

  • SSM Agent requirements:
    • Minimum version 2.3.68.0 for basic session connectivity
    • Version 3.0.222.0 or later for port forwarding and SSH sessions

    Note: Many AWS-provided and trusted third-party Amazon Machine Images (AMIs) come with the SSM Agent pre-installed. For more information, see Find AMIs with the SSM Agent preinstalled.

For a complete list of requirements, see Setting up Session Manager.

Solution overview

This solution, shown in Figure 1, automatically configures the SSM-SessionManagerRunShell document with customizable preferences that govern how Session Manager behaves across your AWS accounts. It creates resources for logging, encryption, and session controls, and updates the SSM-SessionManagerRunShell document with these preferences. The document is updated by an AWS Lambda function that helps make sure that the preferences are correctly applied. It transforms the default Session Manager preferences document to meet your enterprise compliance requirements. Changes are deployed using CloudFormation template provided in the GitHub repository. The solution supports multiple logging destinations, encryption options, and session controls to meet various security and compliance requirements.

Figure 1: Solution overview

Figure 1: Solution overview

Walkthrough

To deploy the solution, complete the following steps.

Step 1: Download or clone the repository

The first step is to download or clone the GitHub repository.

To download the repository:

  1. Go to the main page of the repository on GitHub.
  2. Choose Code and then choose Download ZIP.

To clone the repository:

  1. Make sure that you have Git installed.
  2. Run the following command in your terminal:
    git clone https://github.com/aws-samples/<repo-link>

Step 2: Create the CloudFormation StackSet

In this step, you deploy the solution’s resources by creating a CloudFormation StackSet using the provided CloudFormation template. Sign in to your management account or StackSet delegated admin account. To create the stack, follow the steps in Get started with StackSets using a sample template. Create the StackSet in each of the accounts and Regions where you plan to implement the solution. Note that you need to provide values for the parameters defined in the template to deploy the stack. The following table lists the parameters that you need to provide.

Parameter

Description

S3Logging

Enables storing session logs to an S3 bucket.

S3BucketName

Name of the S3 bucket for session logs. The bucket must exist or the deployment will fail.

S3KeyPrefix

Key prefix for session logs, will be appended by account ID and Region

S3EncryptionEnabled

If set to true, the S3 bucket you specified in the s3BucketName input must be encrypted.

CreateCWLogGroup

Creates the CloudWatch log group. If set to true, a CloudWatch log group will be created; if not, the log group name passed is used.

CWLogGroupName

The name of the CloudWatch log group you want to send session logs to.

CWEncryptionEnabled

If set to true, the CloudWatch log group you specified in the cwLogGroupName input must be encrypted.

CWStreamingEnabled

If set to true, a continual stream of session data logs is sent to the log group.

SessionDataEncryption

If set to true, session data is encrypted with a key created by the stack.

RunAsEnabled

If set to true, sessions are run using another user than ssm-user. The Run As feature is only supported for connecting to Linux and macOS managed nodes.

RunAsDefaultUser

The name of the user account to start sessions with on Linux and macOS managed nodes when the runAsEnabled input is set to true.

IdleSessionTimeout

The amount of time of inactivity you want to allow before a session ends. This input is measured in minutes.

MaxSessionDuration

The maximum amount of time you want to allow before a session ends. This input is measured in minutes.

WinShellProfile

The shell preferences, environment variables, working directories, and commands you specify for sessions on Windows Server managed nodes.

LinuxShellProfile

The shell preferences, environment variables, working directories, and commands you specify for sessions on Linux and macOS managed nodes.

Step 3: Update your EC2 instance profiles with proper permissions

Depending on the parameter values you pass when deploying the template, you need to update your EC2 instance profiles with proper permissions. For example, if you have enabled session data and session log encryption, you need to add the following policy to your instance profiles.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Action": [
                "logs:DescribeLogGroups"
            ],
            "Resource": "*",
            "Effect": "Allow"
        },
        {
            "Action": [
                "logs:DescribeLogStreams"
            ],
            "Resource": "<arn:aws:logs:*:123456789012:log-group:ssm-sessionmanager-logs>",
            "Effect": "Allow"
        },
        {
            "Action": [
                "logs:CreateLogStream",
                "logs:PutLogEvents"
            ],
            "Resource": "arn:aws:logs:*:123456789012:log-group:ssm-sessionmanager-logs:log-stream:*",
            "Effect": "Allow"
        },
        {
            "Condition": {
                "Null": {
                    "kms:ResourceAliases": "false"
                },
                "ForAllValues:StringLike": {
                    "kms:ResourceAliases": [
                        "alias/session-manager/data"
                    ]
                }
            },
            "Action": [
                "kms:Decrypt"
            ],
            "Resource": "arn:aws:kms:us-east-1:123456789012:key/*",
            "Effect": "Allow"
        }
    ]
}

Note: If you enable S3 logging, you need to add the required permissions for that as well. See Configure a central S3 bucket for Session Manager logging article on AWS re:Post for more information about how to properly configure your S3 bucket and EC2 instance profile for centralized logging. Same-account logging follows a similar pattern.

Step 4: Verify the solution implementation

You can verify that the Session Manager preferences are correctly configured across your environment. Here’s a systematic approach to validation:

Verify preference configuration

Through the AWS Management Console, navigate to AWS Systems Manager Session Manager, choose Preferences and review the configured Session Manager preferences. Alternatively, verify the configuration through AWS CLI using:

aws ssm get-document --name "SSM-SessionManagerRunShell" --document-version \$LATEST

Validate session functionality

Start a new session following the AWS Systems Manager User Guide and perform the following validations:

  1. Verify the encryption configuration by starting a new session. If session data encryption is enabled, you should see the message This session is encrypted using AWS KMS when the session begins.
  2. For CloudWatch logging verification, navigate to the CloudWatch console and access the Log groups section. Confirm that your specified log group exists and KMS encryption is enabled if you configured it during deployment. Execute some commands in your session and observe the real-time log streaming to your configured log group.
  3. To verify S3 logging, establish a session and execute several commands. Terminate the session and check your configured S3 bucket for the session logs. Remember that S3 logs are only generated after the session is terminated.
  4. If you enabled the RunAsEnabled option, verify the configuration by executing the whoami command in your session. The output should match your configured RunAs user.

Resources

The following is a list of resources created by this solution:

AWS::Lambda::Function (UpdateSessionManagerFunction)
This resource creates a Lambda function that:

  • Updates the SSM-SessionManagerRunShell document with the specified preferences
  • Handles CloudFormation create, update, and delete events
  • Performs deep comparison of document contents to avoid unnecessary updates
  • Includes error handling and retry logic

AWS::IAM::Role (LambdaExecutionRole)
This resource creates an IAM role that allows the Lambda function to:

  • Execute with basic Lambda permissions
  • Access and modify the SSM-SessionManagerRunShell document
  • Access SSM parameters storing session data encryption key ID

AWS::KMS::Key (SessionDataKMSKey)
This conditional resource creates a KMS key for encrypting session data when SessionDataEncryption parameter is set to enabled. The key has a policy allowing key management with IAM.

AWS::KMS::Alias (SessionDataKeyAlias)
This conditional resource creates a friendly alias (alias/session-manager/data) for the session data encryption key. This value cannot be changed.

AWS::SSM::Parameter (SessionKeyID)
This conditional resource creates an Systems Manager parameter to store the KMS key ID for session data encryption, making it accessible to other components.

Note: The session data KMS key ID is stored in a Systems Manager parameter to decouple components and help prevent circular dependency and failures to due race conditions.

AWS::KMS::Key (SessionLogsKMSKey)
This conditional resource creates a KMS key for encrypting CloudWatch logs when CWEncryptionEnabled parameter is set to enabled. The key has a policy allowing CloudWatch Logs service to use it

Note: SessionLogsKMSKey is used to encrypt logs at-rest and is not used by the SSM Agent, so your instance profile does not need to have permission to this key. Logs are encrypted in-transit and will be encrypted by CloudWatch service after they are received.

AWS::KMS::Alias (SessionLogsKeyAlias)
This conditional resource creates a friendly alias (alias/session-manager/logs) for the CloudWatch Logs encryption key.

AWS::Logs::LogGroup (SessionManagerLogGroup)
This conditional resource creates a CloudWatch Logs group for session logs when the CreateCWLogGroup paremeter is set to enabled. The log group:

  • Uses the specified name (controlled by the CWLogGroupName parameter, and defaults to ssm-sessionmanager-logs)
  • Sets a 90-day retention period
  • Uses KMS encryption if enabled

Custom::UpdateSessionManager (UpdateSessionManagerCustomResource)
This custom resource invokes the Lambda function to update the SSM-SessionManagerRunShell document with the specified preferences.

Parameter groups

The following template parameters are available for customizing Session Manager behavior:

Parameter group

Parameters

Description

S3 logging

S3Logging, S3BucketName, S3KeyPrefix, S3EncryptionEnabled

Controls logging to Amazon S3

CloudWatch logging

CreateCWLogGroup, CWLogGroupName, CWEncryptionEnabled, CWStreamingEnabled

Controls logging to CloudWatch Logs

Encryption

SessionDataEncryption

Controls encryption of session data

Session controls

RunAsEnabled, RunAsDefaultUser, IdleSessionTimeout, MaxSessionDuration

Controls session behavior

Shell profiles

WinShellProfile, LinuxShellProfile

Controls shell environment

Conclusion

In this post, we explored how to implement and manage Session Manager preferences across your organization using CloudFormation StackSets. This solution enables centralized management of Session Manager configurations across multiple accounts and Regions from a single account, significantly simplifying the administration of remote access to your compute resources. Through automated deployment of security controls including session encryption, logging, and access restrictions, the solution helps facilitate consistent compliance with organizational security requirements while reducing manual configuration efforts and the risk of human error. As your organization grows, this solution scales seamlessly to accommodate new accounts and Regions while maintaining uniform security standards across your infrastructure.

Remember to regularly review and update your Session Manager preferences to align with evolving security requirements and organizational needs. For more information about AWS Systems Manager Session Manager, visit the official AWS documentation.

If you have feedback about this post, submit comments in the Comments section below.

Nima Fotouhi

Nima Fotouhi

Nima is a Security Consultant at AWS. He’s a builder with a passion for infrastructure as code (IaC) and policy as code (PaC) and helps customers build secure infrastructure on AWS. In his spare time, he loves to hit the slopes and go snowboarding.

Post-quantum (ML-DSA) code signing with AWS Private CA and AWS KMS

Post Syndicated from Panos Kampanakis original https://aws.amazon.com/blogs/security/post-quantum-ml-dsa-code-signing-with-aws-private-ca-and-aws-kms/

Following our recent announcement of ML-DSA support in AWS Key Management Service (AWS KMS), we just introduced post-quantum ML-DSA signature support in AWS Private Certificate Authority (AWS Private CA). Customers can use AWS Private CA to create and manage their own private public key infrastructure (PKI) hierarchies. Through this integration, you can establish and use customer-managed quantum-resistant roots of trust for code signing, device authentication, outside (of AWS) workload authentication with AWS IAM Roles Anywhere, or communication tunnels such as IKEv2/IPsec or Mutual TLS (mTLS) using private PKI.

As outlined in the AWS post-quantum cryptography migration plan, establishing quantum-resistant roots of trust is critical for systems that need to maintain security for extended periods of time. ML-DSA, a signature scheme standardized in FIPS 204, provides quantum resistance while maintaining the performance characteristics needed for deployments at scale.

Previously, we shared how to use AWS Private CA and AWS KMS for code signing. In this post, we show you how to combine the post-quantum signing capability provided by AWS KMS with post-quantum code-signing PKI from AWS Private CA. Consumers of signed code that have been pre-provisioned with the post-quantum PKI roots can rest assured that the software could not have been forged by an adversary with a cryptographically relevant quantum computer (CRQC). For demonstration purposes, we use the diy-code-signing-kms-private-ca sample program, which uses the AWS SDK for Java. This code creates a PKI infrastructure, generates a code-signing certificate, signs binary code, and verifies the signature. Although we break down the steps to demonstrate the functionality in this post, you can run the Runner as-is to see it in action with commands found in the README file.

This post uses the Cryptographic Message Syntax (CMS) standard for encapsulating the signatures generated for input binary data. It stores the signature, X.509 certificate, and chain used to establish trust. The signature, known as a detached signature, doesn’t contain the original data. The detached signature can be used together with the original file, which was signed with standard tools such as OpenSSL natively to validate the authenticity of the file.

Create a post-quantum PKI hierarchy

For this post, we will use AWS Private CA to introduce a code-signing PKI. It will consist of a root CA to sign a subordinate CA, and a code-signing certificate signed by the subordinate CA. The whole chain will consist of quantum-resistant ML-DSA certificates.

CA hierarchy creation

First, the post-quantum CA hierarchy must be created with ML-DSA. In this example, we use the ML-DSA-65 variant of the post-quantum signature algorithm. You can do this with the AWS Java SDK as shown in the Runner.java file:

PrivateCA rootPrivateCA = PrivateCA.builder()
	.withCommonName(ROOT_COMMON_NAME)
	.withType(CertificateAuthorityType.ROOT)
	.withAlgorithmFamily(ML_DSA_65_ALGORITHM_FAMILY)
	.getOrCreate();

PrivateCA subordinatePrivateCA = PrivateCA.builder()
    .withIssuer(rootPrivateCA).withCommonName(SUBORDINATE_COMMON_NAME)
    .withType(CertificateAuthorityType.SUBORDINATE)
	.withAlgorithmFamily(ML_DSA_65_ALGORITHM_FAMILY)
    .getOrCreate();

Code-signer creation

For code signing, you need an asymmetric key pair and a code-signing certificate. The asymmetric ML-DSA key pair is generated in AWS KMS and the code-signing certificate is issued by AWS Private CA.

Create an ML-DSA key pair in AWS KMS

First, you must create an asymmetric key pair for code signing operations. Similar to the creation of the hierarchy, the AWS Java SDK can be used to create that AWS KMS key (key pair). Signing will be taking place with the key pair’s private key in AWS KMS. The corresponding public key will be in the code-signing leaf certificate signed by the subordinate CA. These calls are performed as part of the main method within the Runner.java file:

AsymmetricCMK codeSigningCMK = AsymmetricCMK
    .builder().withAlias(CMK_ALIAS)
	.withAlgorithmFamily(ML_DSA_65_ALGORITHM_FAMILY)
    .getOrCreate();

Alternatively, you can generate the key pair in AWS KMS with the AWS Management Console or the AWS Command Line Interface (AWS CLI) as shown in the ML-DSA KMS security blog.

Issue a code-signing certificate

Creating a certificate signing request (CSR) using AWS Private CA is a two-step process. First, you must create a CSR that contains both an identity (Subject) and the previously created AWS KMS public key. The following code snippet in Runner.java accomplishes this:

String codeSigningCSR = codeSigningCMK
	.generateCSR(END_ENTITY_COMMON_NAME);

OpenSSL 3.5 or later can parse this CSR to view its content with the following command if the CSR contents have been written to disk at csr.pem:

openssl req -in csr.pem -inform pem -text -noout
Certificate Request:
	Data:
		Version: 1 (0x0)
		Subject: CN=CodeSigningCertificate
		Subject Public Key Info:
			Public Key Algorithm: ML-DSA-65
				ML-DSA-65 Public-Key:
				pub:
					<Public Key Data>   
		Attributes:
			Requested Extensions:
				X509v3 Basic Constraints:
					CA:FALSE
	Signature Algorithm: ML-DSA-65
	Signature Value:
		<Signature Data>

You can see that the CSR contains an ML-DSA-65 public key. Its corresponding private key will be used to sign code.

The CSR is used by the subordinate CA to issue the code-signing certificate. Note that the code-signing template is used in the templateArn of the IssueCertificate request in the relevant PrivateCA.java file. The inclusion of this template helps ensure that AWS Private CA will issue a certificate with the correct Key Usage (KU) and Extended Key Usage (EKU) extension values, regardless of the values presented in the CSR.

IssueCertificateRequest issueCertificateRequest = IssueCertificateRequest.builder()
	.idempotencyToken(UUID.randomUUID().toString())
	.certificateAuthorityArn(subordinatePrivateCA.arn())
	.csr(SdkBytes.fromUtf8String(csr))
	.signingAlgorithm(algorithmFamily.getPcaSigningAlgorithm())
	.templateArn("arn:aws:acm-pca:::template/CodeSigningCertificate/V1")
	.validity(validity)
	.build();

IssueCertificateResponse issueCertificateResponse = client
	.issueCertificate(issueCertificateRequest);

String certificateArn = issueCertificateResponse.certificateArn();

GetCertificateRequest getCertificateRequest = GetCertificateRequest.builder()
	.certificateAuthorityArn(ca.arn())
	.certificateArn(certificateArn)
	.build();

The response includes the ML-DSA-65 code-signing certificate. You can use OpenSSL 3.5 or later to inspect the contents of the certificate after you save it to a file named code-signing-cert.pem:

openssl x509 -in code-signing-cert.pem -inform pem -text -noout
Certificate:
	Data:
		Version: 3 (0x2)
		Serial Number:
			1a:15:af:1e:64:8d:cd:29:b4:dc:66:2a:8b:1e:ee:b0
		Signature Algorithm: ML-DSA-65
		Issuer: CN=CodeSigningSubordinate-MLDSA65
		Validity
			Not Before: Sep 24 13:10:38 2025 GMT
			Not After : Sep 24 14:10:38 2026 GMT
		Subject: CN=CodeSigningCertificate
		Subject Public Key Info:
			Public Key Algorithm: ML-DSA-65
				ML-DSA-65 Public-Key:
				pub:
					<Public Key Data>
		X509v3 extensions:
			X509v3 Basic Constraints:
				CA:FALSE
			X509v3 Authority Key Identifier:
B7:EF:2E:C9:7A:A8:7E:B5:D6:2D:9A:3F:C7:A7:F8:9D:74:01:6A:EF
			X509v3 Subject Key Identifier:

7F:63:35:0C:56:F8:ED:F1:2A:DF:B5:2E:7C:F1:2C:D9:A0:0E:63:B6
			X509v3 Key Usage: critical
				Digital Signature
			X509v3 Extended Key Usage: critical
				Code Signing
	Signature Algorithm: ML-DSA-65
	Signature Value:
		<Signature Data>

You can see that the certificate includes the ML-DSA-65 public key of the code-signing key pair and the ML-DSA-65 signature from the subordinate CA. You also see the KU and the EKU values, which represent a code-signing certificate from the AWS Private CA template.

Sign code

At this point, you have set up the code-signing PKI, have a code-signing certificate issued by AWS Private CA and a corresponding ML-DSA key pair residing in KMS.

The Java SDK can be used to generate a CMS signature for a code binary file. In the background, this is accomplished by calling the AWS KMS Sign API with the ML-DSA key pair as shown in Runner.java. The following is part of the Java code. This first snippet involves building a certificate chain and then using it along with the code-signing AWS KMS key, the signer’s certificate, and <DATA_TO_SIGN>, the byte array representation of the code file, to generate the detached signature in a CMS structure.

	// Parse code-signing certificate from PEM
	X509CertificateHolder signerCert = CertificateUtils
		.fromPEM(codeSigningCertificate.certificate());

	Collection<X509CertificateHolder> chainCerts = CertificateUtils
		.toCertificateHolders(codeSigningCertificate.certificateChain());

	// Build certificate chain including code-signing cert and intermediate certs
	Collection<X509CertificateHolder> certChain = new ArrayList<> ();
	certChain.add(signerCert);

	// Parse certificate chain
	for (X509CertificateHolder chainCert : chainCerts) {
		if (!chainCert.equals(signerCert)) {
			certChain.add(chainCert);
		}
	}

	// Create detached CMS signature
	CMSCodeSigningObject cmsCodeSigningObject = CMSCodeSigningObject
		.createDetachedSignature(
			codeSigningCMK,
			ML_DSA_65_ALGORITHM_FAMILY,
			<DATA_TO_SIGN>,
			signerCert,
			certChain);

The code-signing object is written to disk in signature-MLDSA65.p7s. You can inspect it with OpenSSL 3.5 or later:

openssl cms -cmsout -in signature-MLDSA65.p7s -inform DER -print
CMS_ContentInfo:
	contentType: pkcs7-signedData (1.2.840.113549.1.7.2)
	d.signedData:
		version: 1
		digestAlgorithms:
			algorithm: shake256 (2.16.840.1.101.3.4.2.12)
			parameter: <ABSENT>
		encapContentInfo:
			eContentType: pkcs7-data (1.2.840.113549.1.7.1)
			eContent: <ABSENT>
		certificates:
			d.certificate:
				cert_info:
					version: 2
					serialNumber: 0xD0B2937F5BABC80AD55C0A90E1DE7057
					signature:
						algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
						parameter: <ABSENT>
					issuer:			CN=CodeSigningSubordinate-MLDSA65
					validity:
						notBefore: Oct 28 15:05:27 2025 GMT
						notAfter: Oct 28 16:05:26 2026 GMT
					subject:		CN=CodeSigningCertificate
					key:		X509_PUBKEY:
						algor:
							algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
							parameter: <ABSENT>
						public_key:(0 unused bits)
							...
						issuerUID: <ABSENT>
						subjectUID: <ABSENT>
						extensions:
							object: X509v3 Basic Constraints (2.5.29.19)
							critical: FALSE
							value:
								0000 - 30 00 0.
                                    
							object: X509v3 Authority Key Identifier (2.5.29.35)
							critical: FALSE
							value:
								0000 - 30 16 80 14 b7 ef 2e c9-7a a8 7e b5 d60.......z.~..
								000d - 2d 9a 3f c7 a7 f8 9d 74-01 6a ef-.?....t.j.

                        	object: X509v3 Subject Key Identifier (2.5.29.14)
							critical: FALSE
							value:
								0000 - 04 14 7f 63 35 0c 56 f8-ed f1 2a df b5...c5.V...*..
								000d - 2e 7c f1 2c d9 a0 0e 63-b6.|.,...c.

                         	object: X509v3 Key Usage (2.5.29.15)
							critical: TRUE
							value:
								0000 - 03 02 07 80....
                                    
							object: X509v3 Extended Key Usage (2.5.29.37)
							critical: TRUE
							value:
								0000 - 30 0a 06 08 2b 06 01 05-05 07 03 030...+.......
					sig_alg:
						algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
						parameter: <ABSENT>
					signature:(0 unused bits)
						...
		d.certificate:
			cert_info:
			version: 2
			serialNumber: 29577999257397559174219641462943780786
			signature:
				algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
				parameter: <ABSENT>
				issuer:			CN=CodeSigningRoot-MLDSA65
				[...]
                
		d.certificate:
			cert_info:
			version: 2
			serialNumber: 0xB9419A2C5D2422B3A58A5B449546D74B
			signature:
				algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
				parameter: <ABSENT>
				issuer:			CN=CodeSigningRoot-MLDSA65
				[...]
	crls:
		<ABSENT>
	signerInfos:
		version: 1
		d.issuerAndSerialNumber:
			issuer:				CN=CodeSigningSubordinate-MLDSA65
			serialNumber: 0xD0B2937F5BABC80AD55C0A90E1DE7057
		digestAlgorithm:
			algorithm: shake256 (2.16.840.1.101.3.4.2.12)
			parameter: <ABSENT>
		signedAttrs:
			object: contentType (1.2.840.113549.1.9.3)
			set:
				OBJECT:pkcs7-data (1.2.840.113549.1.7.1)

			object: signingTime (1.2.840.113549.1.9.5)
			set:
				UTCTIME:Oct 28 16:05:27 2025 GMT

			object: id-aa-CMSAlgorithmProtection (1.2.840.113549.1.9.52)
			set:
				SEQUENCE:
	0:d=0hl=2 l=26 cons: SEQUENCE
	2:d=1hl=2 l=11 cons:SEQUENCE
	4:d=2hl=2 l=9 prim:OBJECT:shake256
	15:d=1hl=2 l=11 cons:cont [ 1 ]
	17:d=2hl=2 l=9 prim:OBJECT:ML-DSA-65

        	object: messageDigest (1.2.840.113549.1.9.4)
			set:
				OCTET STRING:
					...
		signatureAlgorithm:
			algorithm: ML-DSA-65 (2.16.840.1.101.3.4.3.18)
			parameter: <ABSENT>
		signature:
			[...]

The CMS signature object directly encapsulates both the code-signing certificate and the subordinate CA certificate. It’s expected that the root certificate will reside in a customer-managed trust store. In addition to these certificates, the CMS object also contains the digest of the input data within the signedAttrs of the signerInfos in the ASN.1 structure. The digest algorithm is SHAKE256 and the OCTET STRING represents the binary digest itself. The use of ML-DSA in CMS is specified in RFC9882.

Note: Although this example uses one ML-DSA signature, some use cases might include dual signatures, a traditional and a quantum-resistant one. Such signed artifacts can be backwards compatible with legacy verifiers that support and can only verify the traditional signature. Upgraded verifiers can verify both signatures.

Verify signed code

Before loading a signed code artifact, its signature needs to be verified. That includes verifying the signature of the code and validating the certificate chain to the trusted root CA. The following code snippet from the main method within the file Runner.java is used for the certificate chain validation and the signature in the code object:

X509CertificateHolder rootCACertificate = CertificateUtils.fromPEM(rootCACertificatePEM); 
cmsCodeSigningObject.verifyDetachedSignature(<DATA_TO_SIGN>, rootCACertificate);

The preceding code retrieves the ML-DSA public key from the code-signing certificate; AWS access or credentials aren’t needed to validate the signature. Entities that have the root CA certificate loaded in their trust store can verify it without needing access to the AWS KMS verify API.

Note: The Runner.java implementation doesn’t use a certificate trust store that’s either part of a browser or part of a file system within the resident operating system of a device or a server. The trust store is placed in an instance of a Java class object for the purpose of this post. If you’re planning to use this code-signing example in a production system, you must change the implementation to use a trust store on the host. To do so, you can build and distribute a secure trust store that includes the root CA certificate.

Alternatively, OpenSSL 3.5 or later can be used to validate the detached signature of the provided input data file with root-ca-MLDSA65.pem, the provided root CA certificate from AWS Private CA.

openssl cms -verify -in signature-MLDSA65.p7s -content <input-data-file> \
            -CAfile root-ca-MLDSA65.pem -inform DER -purpose any \
            -binary -out /dev/null
CMS Verification successful

Note: Although this post focused on code-signing, AWS Private CA can enable post-quantum ML-DSA authentication for other private PKI use cases. In one scenario, applications outside of AWS can access AWS resources by temporarily using certificate-based authentication and swapping it with AWS credentials with AWS IAM Roles Anywhere. AWS IAM Roles Anywhere now supports ML-DSA PKIs like the one created in this post. In another scenario, an mTLS client or IKEv2/IPsec peer could use an ML-DSA certificate issued by AWS Private CA to be authenticated by a server or peer respectively who has been pre-provisioned with the post-quantum PKI root certificate.

Conclusion

This announcement marks an important milestone for post-quantum authentication. With the introduction of ML-DSA X.509 certificates in AWS Private CA, customers can bring quantum resistance to their private PKI use cases. These use cases include client authentication for mTLS or IKEv2/IPsec tunnels, IAM Roles Anywhere, or applications that use private PKI authentication. ML-DSA certificates with AWS Private CA and signing with AWS KMS also enable post-quantum code-singing and establishing post-quantum long-lived roots of trust for devices designed to operate for a long time even after CRQCs became available. Learn more about post-quantum cryptography in general and the overall AWS plan to migrate to post-quantum cryptography.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support. For more details regarding AWS PQC efforts, refer to our PQC page.
 

Panos Kampanakis

Panos Kampanakis

Panos is a Principal Security Engineer at AWS. He has experience with cybersecurity, applied cryptography, security automation, and vulnerability management. He has coauthored publications on cybersecurity and participated in various security standards bodies to provide common interoperable protocols and languages for security information sharing, cryptography, and public-key infrastructure. Currently, he works with engineers and industry standards partners to provide cryptographically secure tools, protocols, and standards.

Jake Massimo

Jake Massimo

Jake is a Senior Applied Scientist on the AWS Cryptography team. His work interfaces Amazon with the global cryptographic community through international conferences, academic literature, and standards organizations and influences the adoption of post-quantum cloud-scale cryptographic technology. Recently, his focus has been architecting AWS post-quantum cryptographic capabilities, including core libraries and infrastructure so that AWS and customers can seamlessly transition to quantum-safe cryptography.

Author

Kyle Schultheiss

Kyle is a Senior Software Engineer on the AWS Cryptography team. He has been working on the AWS Private Certificate Authority service since its inception in 2018. In prior roles, he contributed to other AWS services such as Amazon Virtual Private Cloud, Amazon EC2, and Amazon Route 53.

AWS re:Invent 2025: Your guide to security sessions across four transformative themes

Post Syndicated from Rahul Sahni original https://aws.amazon.com/blogs/security/aws-reinvent-2025-your-guide-to-security-sessions-across-four-transformative-themes/

AWS re:Invent 2025, the premier cloud computing conference hosted by Amazon Web Services (AWS), returns to Las Vegas, Nevada, December 1–5, 2025. At AWS, security is our top priority, and re:Invent 2025 reflects this commitment with our most comprehensive security track to date. With more than 80 security aligned sessions spanning breakouts, workshops, chalk talks, and hands-on builders’ sessions, we’re bringing together the brightest minds to share insights, best practices, and innovative solutions. For security professionals, developers, and cloud architects, the event offers valuable insights into the latest security innovations at AWS, advanced threat protection capabilities, and defense strategies that scale. While attending re:Invent, you can visit the Security kiosk and AI Security kiosk at the expo hall to engage directly with AWS security experts about your specific needs.

The security track session selection process was driven by our extensive analysis of customer needs and real-world implementation challenges. We specifically focused on security areas where customers seek the most guidance and coalesced the sessions around four major themes: Securing and Leveraging AI, Architecting Security and Identity at scale, Building and scaling a Culture of Security, and Innovations in AWS Security. Our goal with the sessions is to address immediate security challenges and help you achieve broader business outcomes. In the following sections, we highlight a few key sessions in each of the four themes. You can visit the re:Invent catalog for a view of all sessions.

Securing and leveraging AI

Securing and using AI emerges as a dominant theme for the Security and Identity track, reflecting both the opportunities and challenges AI presents. From protecting AI workloads to harnessing AI for enhanced security operations, sessions span multiple AI topics to help organizations navigate this transformative technology safely and effectively. Here are a few key sessions on each of the AI topics.

Securing AI workloads

  • Breakout SEC410 – Advanced AI Security: Architecting Defense-in-Depth for AI Workloads: Dive deep into advanced security architectures for AI workloads, exploring how to protect your workload against sophisticated attack vectors. Through technical examples, we’ll implement secure architectures for AI workloads, covering identity, fine-grained access policies, and secure foundation model deployment patterns. Learn how to harden generative and agentic AI applications using AWS security capabilities, implementing least-privilege controls, and building secure architectures at scale.
  • Workshop SEC406 – Red teaming your generative AI and MCP applications at scale: Step into the shoes of an AI-powered red team adversary in the GenAI Red Team Challenge. In this intensive workshop, you’ll deploy an AI security agent to orchestrate sophisticated threat chains against Model Context Protocol (MCP) applications, systematically discovering vulnerabilities. Master countermeasures from prompt templating and guardrails to OAuth-enhanced MCP security configurations that prevent unauthorized access. This hands-on, gamified experience helps you think like a threat actor and equips you with practical skills in automated vulnerability testing and risk mitigation against common MITRE and OWASP vulnerabilities for LLM-based applications. You must bring your laptop to participate.

Security for Agentic AI

  • ChalkTalk SEC408 – Securing Agentic AI: OWASP, MAESTRO, and Real-World Defense Strategies: Explore the latest in Agentic AI security with OWASP’s updated Threats and Mitigations Guide and Agentic Security Initiative. We will also explore MAESTRO, a specialized threat modeling approach for AI systems, offering a layered methodology to identify and mitigate risks throughout the AI lifecycle. Through a real-world case study, we’ll demonstrate security best practices for agentic AI, including robust governance, continuous monitoring, and least-privilege access. Learn how to confidently deploy autonomous AI agents while minimizing risks. Gain practical insights for building secure, trustworthy, and resilient agentic AI applications that can transform industries safely.
  • Workshop SEC307 – Design authentication, authorization, and logging logic in Agentic AI apps: This hands-on workshop addresses the critical challenge of managing identities and permissions for generative AI agents. Learn to implement user and machine authentication, along with fine-grained authorization mechanisms, tailored for AI agents, tools, and LLMs. Explore consent management and permission delegation in AI contexts. Participants will gain practical experience using AWS’s latest services, including Strands SDK, Amazon Bedrock AgentCore Identity, Amazon Cognito for identity management, and Amazon Verified Permissions for authorization decisions. By the end, you’ll have the skills to enhance security and compliance in your AI operations using AWS’s cutting-edge identity and access management solutions.

Using AI for security

  • Builders SEC318 – Strengthen your network security with generative AI: Transform how you manage network security using the power of generative AI. See how Amazon Q Developer helps you explore AWS Shield Network Security Director findings through natural language conversations. Learn to quickly identify misconfigured resources, understand security issues, and implement guided fixes across your AWS environment.
  • Chalktalk SEC304 – Building an AI-Powered security guardian for your Cognito applications: Elevate your application security with an intelligent AI-Powered security guardian to protect your Amazon Cognito-authenticated applications. In this interactive session, we’ll explore identity best practices and building an AI agent using Amazon Bedrock AgentCore to help verify best practices, perform detective analysis, and take automated preventative actions to mitigate risks. We’ll talk through how an AI agent can perform dynamic WAF rule adjustments, modify authentication flows, and perform security operations center (SOC) actions. Bring your questions and scenarios as we deep dive into how to implement AI-driven security controls for your Cognito protected applications.

Building and Scaling Culture of Security

This theme is woven throughout the re:Invent 2025 security track, reflecting the belief that technological solutions alone cannot ensure robust security outcomes. Enterprises with a Culture of Security become security-first organizations, after which they can accelerate secure digital transformations. Some of the sessions that showcase this theme are:

  • Breakout SEC319 – Climbing the AI Mountain With Your Security Team: Navigate the intersection of AI and security culture in this practical session. Learn how security teams can effectively embrace AI innovation through incremental steps and validation techniques. Using real-world examples, we’ll demonstrate how security practitioners can adapt their skills to AI challenges regardless of their level of specialized expertise and share strategies for building security-aware AI practices. From understanding generative and agentic AI-specific security risks to creating engaging team exercises, discover how to transform security from a potential bottleneck into an enabler of responsible AI innovation. Attendees will leave with actionable insights for building a security-first approach to AI adoption.
  • Chalktalk SEC343 – Fostering a Resilient Incident Response Culture: Discover how to combine human expertise with intelligent automation in security incident response. Learn how AWS Security Incident Response, auto-triaging capabilities, and generative AI work together to augment—not replace—your team’s decision-making. We’ll explore how integrating AWS Security Incident Response and generative AI into your workflows can reduce alert fatigue, accelerate accurate incident classification, and enable responders to focus on critical analysis. See how leading organizations balance automation with human oversight, creating more efficient and resilient incident response processes while maintaining the crucial elements of human judgment and institutional knowledge. Uncover practical strategies for integrating AI-driven insights with human expertise in your incident response culture.
  • Chalktalk SEC227 – Translating Security Metrics into Business Outcomes: Today CISOs face the challenge of translating complex security data into business value. This session reveals proven frameworks for transforming security metrics into strategic insights that drive boardroom decisions. Learn how leading organizations leverage AWS Security Hub, OpenSearch and Security Analytics and automation to build real-time risk dashboards that demonstrate security’s business impact. Walk away with practical strategies for evolving your security program from operational metrics to business outcomes, enabling data-driven investment decisions and measurable risk reduction that resonates with executives.

Architecting Security and Identity at scale

This theme explores how you can use the comprehensive toolset and proven patterns provided by AWS to implement enterprise-grade security controls that scale from individual workloads to global organizations. Some key sessions on this theme include:

  • ChalkTalk SEC333 – From Static to Dynamic: Modernizing AWS Access Management: Building a robust AWS identity foundation requires moving beyond static credentials. This session deep dives into proven patterns for implementing dynamic, temporary access across your AWS organization. We’ll explore real-world challenges of access key dependencies and share practical approaches to transition towards ephemeral credentials using IAM roles and SAML federation. Through practical examples and lessons learned, discover how to implement secure authentication patterns that scale while reducing operational overhead. Walk away with actionable strategies to strengthen your identity perimeter and modernize your access management approach.
  • Workshop SEC401 – Active defense strategies using AWS Al/ML services: This workshop will help you learn how to develop and deploy active defense strategies, such as deception, using Amazon Bedrock and Amazon SageMaker. Gain hands-on experience developing AI-driven responses for security operations. You will learn how to develop adaptive responses that mimic what an actor may be trying use against you. Discover implementation patterns for prompt engineering, deployment strategies, and monitoring methodologies. You must bring your laptop to participate.
  • Workshop SEC303 – Advanced AWS Network Security: Building Scalable Production Defenses: In this hands-on workshop, master AWS network security techniques to defend against today’s most critical threats. Learn to implement layer 7 capabilities and deep packet inspection using AWS Network Firewall and Route 53 Resolver DNS Firewall, securing both internet-bound and internal traffic flows. Gain practical experience in configuring scalable, reliable filtering to combat zero-day attacks and ransomware, while also implementing sophisticated east-west traffic controls to prevent lateral movement. Through real-world scenarios, you’ll learn to leverage IDS/IPS filtering, domain-based controls, and principle of least privilege using fully managed AWS services. Leave equipped to build resilient network defenses against modern cyber threats.

Innovations in AWS Security

AWS innovation in security capabilities is designed to help organizations outpace evolving threats. From advanced threat detection powered by machine learning to revolutionary data protection mechanisms, these innovations demonstrate the AWS commitment to keeping customers secure in an evolving landscape. Some of the innovation-focused sessions are:

  • Breakout SEC203 – State of the Art: AWS data protection in 2025 (ft. Vanguard): Join AWS Cryptography leaders for a comprehensive tour of 2025’s groundbreaking security innovations. Discover the latest launches across Cloudfront, KMS, Private CA, and Secrets Manager, showcasing AWS’s implementation of NIST-standardized post quantum cryptography. Learn how we’re revolutionizing cloud security through quantum-resistant algorithms, advanced certificate management, and automated secrets handling. Get an inside look at Vanguards enterprise-wide PQC migration and how they made it a strategic business priority. See firsthand how AWS continues raising the bar on data protection for your most sensitive workloads.
  • Breakout SEC323 – AWS detection and response innovations that drive security outcomes: Discover how the latest AWS detection and response capabilities can help secure your cloud environment more effectively. Learn practical ways to achieve integrated security outcomes through enhanced threat detection, automated vulnerability management, and streamlined response—all at scale. We’ll show you how to use AWS security services to protect workloads and data, centralize security monitoring, manage security posture continuously, and unify security data, while leveraging generative AI for security operations. Walk away with actionable insights for integrating AWS detection and response services to strengthen and simplify security across your AWS environment.
  • Breakout SEC310 – Innovations in Infrastructure Protection to strengthen your network: In this session, learn about new capabilities in infrastructure protection services like AWS Network Firewall, Amazon Route 53 DNS Firewall, AWS WAF, and AWS Shield, to simplify your application protection, streamline robust egress protections and gain insight into your network. Dive deep into how new visibility investments can give insight into misconfigurations, possible threats, and proactive identification of network configuration issues.

Conclusion

Don’t miss this opportunity to enhance your cloud security knowledge and connect with AWS security experts and industry peers. For a full view of the Security and Identity sessions, explore the AWS re:invent catalog where you can filter sessions by topic, areas of interest, role, and so on.

When you register, you’ll gain access to the session reservation system where you can reserve your seats. Popular security sessions, especially hands-on sessions, fill up quickly because of limited capacity, so we recommend reserving your preferred sessions as soon as scheduling opens. See you are re:Invent!

If you have feedback about this post, submit comments in the Comments section below.

Rahul Sahni

Rahul Sahni

Rahul is a Senior Product Marketing Manager at AWS Security. An avid Amazonian, Rahul embodies the company’s principle of Learn and Be Curious in both his professional and personal life. With a passion for continuous learning, he thrives on new experiences and adventures. Outside of his professional work, he enjoys experimenting with new dishes from around the world.

Justin Criswell

Justin Criswell

Justin is a Senior Manager of Security Solutions Architecture at AWS. He brings 21 years of technology expertise, including 13 years specializing in cloud security and customer success. He leads a team of specialists and the AWS security field community to help customers adopt and operationalize security services, increase visibility, reduce risk, and enhance their security posture in the AWS Cloud.

Amazon Inspector detects over 150,000 malicious packages linked to token farming campaign

Post Syndicated from Chi Tran original https://aws.amazon.com/blogs/security/amazon-inspector-detects-over-150000-malicious-packages-linked-to-token-farming-campaign/

Amazon Inspector security researchers have identified and reported over 150,000 packages linked to a coordinated tea.xyz token farming campaign in the npm registry. This is one of the largest package flooding incidents in open source registry history, and represents a defining moment in supply chain security, far surpassing the initial 15,000 packages reported by Sonatype researchers in April 2024. Through a combination of advanced rule-based detection and AI, the research team uncovered a self-replicating attack pattern where threat actors automatically generate and publish packages to earn cryptocurrency rewards without user awareness, revealing how the campaign has expanded exponentially since its initial identification.

This incident demonstrates both the evolving nature of threats where financial incentives drive registry pollution at unprecedented scale, and the critical importance of industry-community collaboration in defending the software supply chain. The Amazon Inspector team’s capability to detect subtle, non-traditional threats through innovative detection methodologies, combined with rapid collaboration with the Open Source Security Foundation (OpenSSF) to assign malicious package identifiers (MAL-IDs) and coordinate response, provides a blueprint for how security organizations can respond swiftly and effectively to emerging attack vectors. As the open source community continues to grow, this case serves as both a warning that new threats will emerge wherever financial incentives exist, and a demonstration of how collaborative defense can help address supply chain attacks.

Detection

On October 24, 2025, Amazon Inspector security researchers deployed a new detection rule—paired with AI—to identify additional suspicious package patterns in the npm registry. Within days, the system began flagging packages linked to the tea.xyz protocol—a blockchain-based system designed to reward open source developers.

By November 7, the researchers flagged thousands of packages and began investigating what appeared to be a coordinated campaign. The next day, after validating the evaluation results and analyzing the patterns, they reached out to OpenSSF to share their findings and coordinate a response. With OpenSSF’s review and alignment, Amazon Inspector security researchers began systematically submitting discovered packages to the OpenSSF malicious packages repository, with each package receiving a MAL-ID within 30 minutes. The operation continued through November 12, ultimately uncovering over 150,000 malicious packages.

Here’s what the investigation revealed:

  • Over 150,000 packages linked to the tea.xyz token farming campaign
  • Self-replicating automation that creates packages without legitimate functionality
  • Systematic inclusion of tea.yaml files that link packages to blockchain wallet addresses
  • Coordinated publishing activity across multiple developer accounts

Unlike traditional malware, these packages do not contain overtly malicious code. Instead, they exploit the tea.xyz reward mechanism by artificially inflating package metrics through automated replication and dependency chains, allowing threat actors to extract financial benefits from the open source community.

Token farming as a new attack vector

This campaign represents a concerning evolution in supply chain security. Although the packages might not steal credentials or deploy ransomware, they pose significant risks:

  • Registry pollution – The npm registry is flooded with low-quality, non-functional packages that obscure legitimate software and degrade trust in the open source community.
  • Resource exploitation – Registry infrastructure, bandwidth, and storage are consumed by packages created solely for financial gain rather than genuine contribution.
  • Precedent for abuse – The success of this campaign could inspire similar exploitation of other reward-based systems, normalizing automated package generation for financial gain.
  • Supply chain risk – Even packages that seem benign can add unnecessary dependencies, potentially introducing unexpected behaviors or creating confusion in dependency resolution.

Collaboration with OpenSSF: rapid response

The collaboration between Amazon Inspector security researchers and OpenSSF led to swift action and benefits such as the following:

  • Immediate threat intelligence sharing – The researchers’ findings were shared with OpenSSF’s malicious packages repository, providing the community with comprehensive threat data.
  • MAL-ID assignment – OpenSSF rapidly assigned MAL-IDs to the detected packages, enabling community-wide blocking and remediation. Average time of assignment was 30 minutes.
  • Coordinated disclosure – Both organizations worked together to inform the broader open source community about the threat.
  • Enhanced detection standards – Insights from this campaign are informing improved detection capabilities and policy recommendations across the open source security community.

This collaboration exemplifies how industry leaders and community organizations can work together to help protect software supply chains. The rapid assignment of MAL-IDs demonstrates OpenSSF’s commitment to maintaining the integrity of open source registries, while the researchers’ detection work and threat intelligence provide the advanced insights needed to stay ahead of evolving attack patterns.

Technical details: how the researchers detected the campaign

Amazon Inspector security researchers used a combination of rule-based detection paired with AI-powered techniques to uncover this campaign. The researchers developed pattern matching rules to identify suspicious characteristics such as the following:

  • Presence of tea.yaml configuration files
  • Minimal or cloned code with no original functionality
  • Predictable naming patterns and automated generation signatures
  • Circular dependency chains between related packages

By monitoring publishing patterns, the researchers revealed coordinated campaigns that used automated tooling to create packages at automated speeds.

How to respond to these types of events

You should follow your standard incident response process for active incidents to resolve the issue.

To sweep your development environment, we recommend the following steps:

  • Use Amazon Inspector – Check the findings for packages that are linked to tea.xyz token farming and follow recommended remediation.
  • Audit packages – Remove low-quality, non-functional packages.
  • Harden supply chains – Enforce software bills of materials (SBOMs), pin package versions, and isolate continuous integration and continuous delivery (CI/CD) environments.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, add a note in AWS re:Post tagged with Amazon Inspector, or contact AWS Support.


Chi Tran
Chi Tran

Chi is a Senior Security Researcher at Amazon Web Services, specializing in open-source software supply chain security. He leads the R&D of the engine behind Amazon Inspector that detects malicious packages in open-source software. As an Amazon Inspector SME, Chi provides technical guidance to customers on complex security implementations and advanced use cases. His expertise spans cloud security, vulnerability research, and application security. Chi holds industry certifications including OSCP, OSCE, OSWE, and GPEN, has discovered multiple CVEs, and holds pending patents in open-source security innovation.
Charlie Bacon
Charlie Bacon

Charlie is Head of Security Engineering and Research for Amazon Inspector at AWS. He leads the teams behind the vulnerability scanning and inventory collection services which power Amazon Inspector and other Amazon Security vulnerability management tools. Before joining AWS, he spent two decades in the financial and security industries where he held senior roles in both research and product development.