Tag Archives: Technical How-to

Ensure Code Integrity for AWS Lambda Functions with Automated Code Signing Using Terraform

Post Syndicated from Sourav Kundu original https://aws.amazon.com/blogs/devops/ensure-code-integrity-for-aws-lambda-functions-with-automated-code-signing-using-terraform/

Authors: Sourav Kundu and Joyson Neville Lewis.

In today’s cloud-native landscape, ensuring the integrity and authenticity of your serverless functions is critical for maintaining security and compliance. Organizations face increasing challenges in preventing the execution of tampered or malicious code in their AWS Lambda functions. These challenges intensify as deployment pipelines become more complex and distributed.

AWS Lambda code signing provides a robust security mechanism that guarantees only trusted, unmodified code executes in your Lambda functions. By implementing digital signatures, you can verify code integrity and authenticate the source, creating a secure foundation for your serverless applications.

This post shows you how to implement AWS Lambda code signing using Terraform, creating an automated, end-to-end security framework that prevents unauthorized code execution while maintaining operational efficiency.

Solution overview

This solution creates a comprehensive code signing pipeline that automatically signs Lambda deployment packages and enforces signature validation at runtime. The implementation uses AWS Signer with the SHA384-ECDSA algorithm for cryptographic security, combined with Terraform automation for consistent deployments across environments.
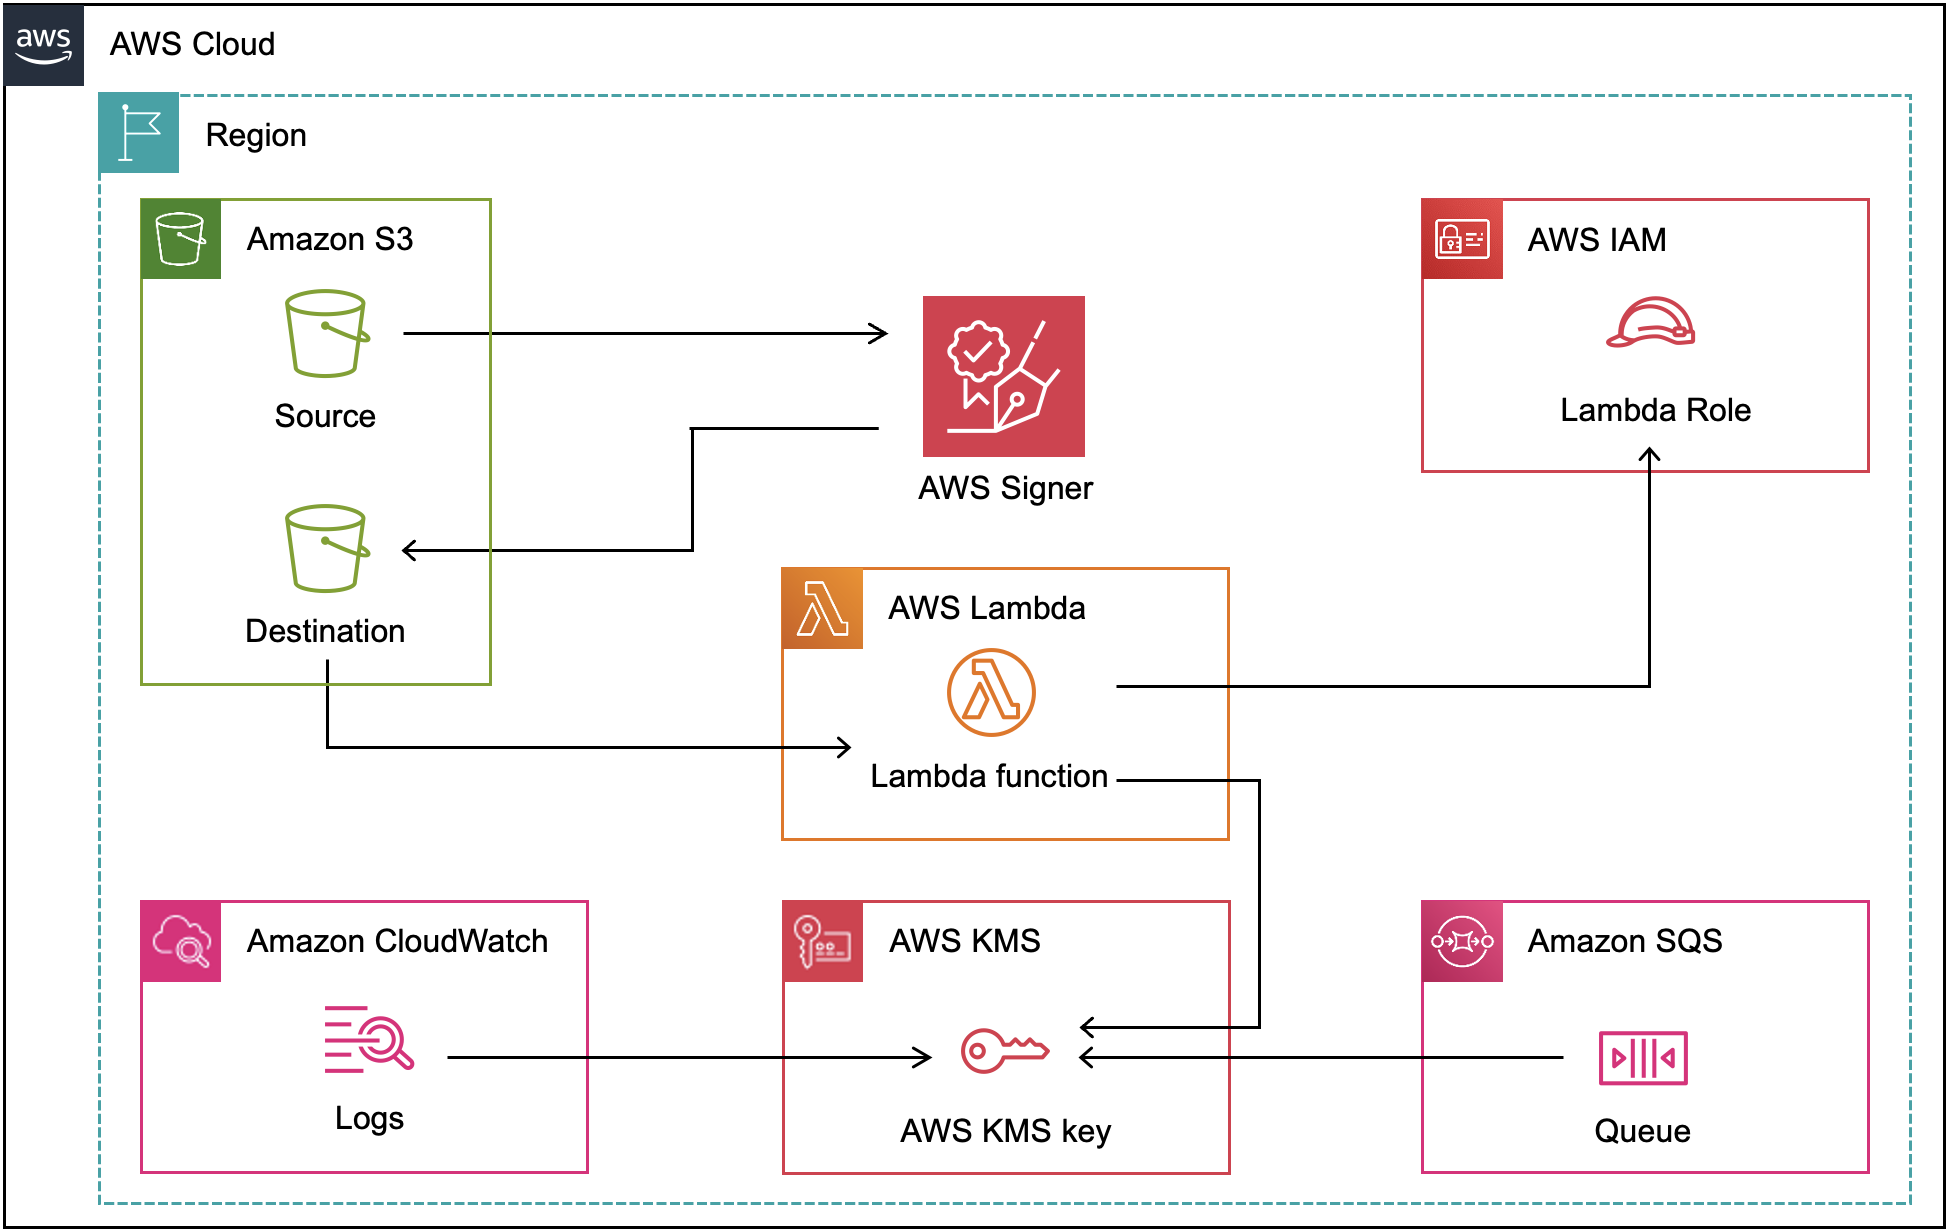
Figure 1: Architecture diagram of AWS Lambda signing with AWS Signer

Figure 1: Architecture diagram of AWS Lambda signing with AWS Signer

The architecture includes:

AWS Signer: Creates signing profiles and jobs with strong cryptographic algorithms

Amazon S3: Stores original and signed Lambda code with versioning enabled

AWS Lambda: Deployed with code signing enforcement in a VPC environment

AWS KMS: Provides encryption for CloudWatch logs and SQS dead letter queue

VPC Configuration: Isolates Lambda execution in private subnets with VPC endpoints

Walkthrough

This walkthrough demonstrates how to deploy a secure Lambda function with code signing enabled using Terraform, a popular infrastructure as code.

The deployment process includes these key steps:

  1. Set up AWS Signer signing profile with cryptographic configuration
  2. Create S3 bucket with versioning for code storage
  3. Configure automated code signing jobs
  4. Secure Lambda deployment
  5. Implement security best practices including KMS encryption and VPC isolation
  6. Deploy the infrastructure with Terraform

Link to GitHub repository: AWS Lambda Code Signing with Terraform.

Prerequisites

For this walkthrough, you should have the following prerequisites:

– An AWS account with appropriate permissions for AWS Signer, Lambda, S3, and VPC services

– Terraform >= 1.0 installed on your local machine

– AWS CLI configured with credentials that have necessary service permissions

– Basic understanding of AWS Lambda, Terraform, and infrastructure as code concepts

1. Setup AWS Signer Signing Profile

The foundation of our code signing implementation starts with creating an AWS Signer signing profile. This profile is the identity that defines the cryptographic algorithm and signature validity period.

1.1 Define the signing profile resource in your Terraform configuration:

   resource "aws_signer_signing_profile" "lambda_signing_profile" {
     platform_id = "AWSLambda-SHA384-ECDSA"
     name        = "${replace(var.name, "-", "_")}_lambda_signing_profile_${random_string.suffix.result}"
     signature_validity_period {
       value = 135
       type  = "MONTHS"
     }
   }

We use the AWSLambda-SHA384-ECDSA platform, which provides strong cryptographic security with SHA-384 hashing and ECDSA (Elliptic Curve Digital Signature Algorithm).

1.2 Configure the code signing configuration that enforces security policies:

   resource "aws_lambda_code_signing_config" "configuration" {
     allowed_publishers {
       signing_profile_version_arns = [aws_signer_signing_profile.lambda_signing_profile.version_arn]
     }
     policies {
       untrusted_artifact_on_deployment = "Enforce"
     }
     description = "Code signing configuration for ${var.name} Lambda function."
   }

The untrusted_artifact_on_deployment = "Enforce" policy ensures that Lambda rejects any unsigned or improperly signed code.

2. Create S3 bucket with versioning for code storage

Before the code can be signed, it needs to be packaged and stored in a versioned S3 bucket. AWS Signer requires S3 versioning to uniquely identify the source artifact for each signing job.

2.1 Create the S3 bucket with versioning enabled:

resource "aws_s3_bucket" "lambda_source" {
  bucket        = "${var.name}-lambda-source-${data.aws_caller_identity.current.account_id}"
  force_destroy = true
}

resource "aws_s3_bucket_versioning" "lambda_source" {
  bucket = aws_s3_bucket.lambda_source.id
  versioning_configuration {
    status = "Enabled"
  }
}

Versioning is not optional here — AWS Signer uses the S3 object version_id to reference the exact artifact to sign.

2.2 Package the Lambda function code and upload it to the bucket:

data "archive_file" "python_file" {
  type        = "zip"
  source_dir  = "${path.module}/lambda_function/"
  output_path = "${path.module}/lambda_function/lambda_function.zip"
}

resource "aws_s3_object" "lambda_zip" {
  bucket     = aws_s3_bucket.lambda_source.bucket
  key        = "lambda_function.zip"
  source     = data.archive_file.python_file.output_path
  etag       = filemd5(data.archive_file.python_file.output_path)
  depends_on = [aws_s3_bucket_versioning.lambda_source]
}

The archive_file data source zips the contents of the lambda_function/ directory, and the aws_s3_object uploads it to the versioned bucket. The depends_on ensures versioning is active before the upload, so the object gets a version_id that the signing job can reference.

3. Configure automated Code Signing jobs

The next step creates an automated signing job that processes your Lambda code and generates signed artifacts.

3.1 Upload your Lambda code and configure the signing job:

   resource "aws_signer_signing_job" "build_signing_job" {
     profile_name = aws_signer_signing_profile.lambda_signing_profile.name

     source {
       s3 {
         bucket  = aws_s3_bucket.lambda_source.bucket
         key     = aws_s3_object.lambda_zip.key
         version = aws_s3_object.lambda_zip.version_id
       }
     }

     destination {
       s3 {
         bucket = aws_s3_bucket.lambda_source.bucket
         prefix = "signed/"
       }
     }
   }

This signing job automatically processes the uploaded Lambda code, creating a signed version stored in the signed/ prefix of your S3 bucket.

4. Secure Lambda Deployment

The Lambda function is configured to use the signed code and enforce code signing.

4.1 Deploy the Lambda function using the signed artifact:

resource "aws_lambda_function" "lambda_run" {
  s3_bucket        = aws_signer_signing_job.build_signing_job.signed_object[0].s3[0].bucket
  s3_key           = aws_signer_signing_job.build_signing_job.signed_object[0].s3[0].key
  source_code_hash = data.archive_file.python_file.output_base64sha256
  function_name    = var.name
  role             = aws_iam_role.lambda_role.arn
  handler          = "handler.lambda_handler"
  runtime          = "python3.12"
  
  code_signing_config_arn = aws_lambda_code_signing_config.configuration.arn
  
  kms_key_arn = aws_kms_key.encryption.arn
  vpc_config {
    subnet_ids         = aws_subnet.private[*].id
    security_group_ids = [aws_security_group.lambda.id]
  }
  tracing_config {
    mode = "Active"
  }
  dead_letter_config {
    target_arn = aws_sqs_queue.dlq.arn
  }
}

The s3_bucket and s3_key reference the signed artifact produced by the signing job. Terraform resolves aws_signer_signing_job.build_signing_job.signed_object[0].s3[0] to the output location where AWS Signer wrote the signed package in step 3. This ensures Lambda always deploys the signed version, never the unsigned source.

The code_signing_config_arn ties the Lambda function to the code signing configuration from step 1. At deploy time, Lambda validates the artifact’s signature against the allowed publishers in that configuration. If the signature is missing, expired, or from an untrusted profile, the deployment is rejected.

5. Implement Security Best Practices

This implementation includes additional security layers beyond code signing to create a comprehensive security framework.

5.1 Create a KMS key with automatic key rotation and a least-privilege policy:

resource "aws_kms_key" "encryption" {
  enable_key_rotation     = true
  description             = "Key to encrypt all the cloud resources in ${var.name}."
  deletion_window_in_days = var.deletion_window_in_days
}

data "aws_iam_policy_document" "encryption_policy" {
  statement {
    sid    = "Enable IAM User Permissions"
    effect = "Allow"
    principals {
      type        = "AWS"
      identifiers = ["arn:aws:iam::${data.aws_caller_identity.current.account_id}:root"]
    }
    actions = [
      "kms:Encrypt", "kms:Decrypt", "kms:ReEncrypt*",
      "kms:GenerateDataKey*", "kms:DescribeKey",
      "kms:Create*", "kms:Enable*", "kms:List*",
      "kms:Put*", "kms:Update*", "kms:Revoke*",
      "kms:Disable*", "kms:Get*", "kms:Delete*",
      "kms:ScheduleKeyDeletion", "kms:CancelKeyDeletion",
      "kms:TagResource", "kms:UntagResource"
    ]
    resources = [aws_kms_key.encryption.arn]
  }
  statement {
    sid    = "Allow CloudWatch to use the key"
    effect = "Allow"
    principals {
      type        = "Service"
      identifiers = ["logs.amazonaws.com"]
    }
    actions = [
      "kms:Encrypt", "kms:Decrypt", "kms:ReEncrypt*",
      "kms:GenerateDataKey*", "kms:DescribeKey", "kms:CreateGrant"
    ]
    resources = [aws_kms_key.encryption.arn]
    condition {
      test     = "ArnEquals"
      variable = "kms:EncryptionContext:aws:logs:arn"
      values   = [local.cloudwatch_log_group_arn]
    }
  }
  statement {
    sid    = "Allow Lambda to use the key"
    effect = "Allow"
    principals {
      type        = "Service"
      identifiers = ["lambda.amazonaws.com"]
    }
    actions = [
      "kms:Encrypt", "kms:Decrypt", "kms:ReEncrypt*",
      "kms:GenerateDataKey*", "kms:DescribeKey", "kms:CreateGrant"
    ]
    resources = [aws_kms_key.encryption.arn]
    condition {
      test     = "StringEquals"
      variable = "kms:EncryptionContext:LambdaFunctionName"
      values   = [var.name]
    }
    condition {
      test     = "StringEquals"
      variable = "aws:RequestedRegion"
      values   = [var.region]
    }
  }
}

resource "aws_kms_key_policy" "encryption" {
  key_id = aws_kms_key.encryption.id
  policy = data.aws_iam_policy_document.encryption_policy.json
}

The enable_key_rotation = true setting enables automatic annual key rotation, a recommended security practice. The policy uses aws_iam_policy_document instead of inline JSON for better readability and validation. Each statement is scoped to a specific principal: the root account gets administrative access with enumerated actions (not kms:*), CloudWatch Logs can only use the key for the specific log group via the kms:EncryptionContext:aws:logs:arn condition, and Lambda access is constrained to the specific function name and region. This ensures no service can use the key beyond its intended scope.

5.2 Configure VPC with private subnets for Lambda isolation:

resource "aws_vpc" "main" {
  cidr_block           = var.vpc_cidr
  enable_dns_hostnames = true
  enable_dns_support   = true
}

resource "aws_subnet" "private" {
  count             = length(var.subnet_cidr_private)
  vpc_id            = aws_vpc.main.id
  cidr_block        = var.subnet_cidr_private[count.index]
  availability_zone = data.aws_availability_zones.available.names[count.index]
}

The enable_dns_hostnames and enable_dns_support settings are required for VPC endpoints to resolve via private DNS.

5.3 Add VPC endpoints so the Lambda function can reach CloudWatch Logs and SQS from the private subnets without internet access:

resource "aws_vpc_endpoint" "logs" {
  vpc_id              = aws_vpc.main.id
  service_name        = "com.amazonaws.${var.region}.logs"
  vpc_endpoint_type   = "Interface"
  subnet_ids          = aws_subnet.private[*].id
  security_group_ids  = [aws_security_group.endpoint_sg.id]
  private_dns_enabled = true
}

resource "aws_vpc_endpoint" "sqs" {
  vpc_id              = aws_vpc.main.id
  service_name        = "com.amazonaws.${var.region}.sqs"
  vpc_endpoint_type   = "Interface"
  subnet_ids          = aws_subnet.private[*].id
  security_group_ids  = [aws_security_group.endpoint_sg.id]
  private_dns_enabled = true
}

The Lambda function uses an SQS dead letter queue and hence requires the SQS endpoint. The private_dns_enabled setting allows the Lambda function to reach these services using their standard endpoints without any code changes. For the complete networking configuration including security groups and route tables, see the GitHub repository.

These security measures create defense in depth, combining code signing with encryption, network isolation, and secure communication channels.

6. Deploy the Infrastructure

With all the resources defined, initialize and deploy the complete infrastructure:

terraform init
terraform plan
terraform apply

The terraform init command downloads the required providers. The terraform plan command previews all the resources that will be created, and terraform apply provisions the entire stack — signing profile, S3 bucket, signing job, Lambda function, and all supporting infrastructure — in the correct dependency order.

Verification

After the deployment completes, verify that the signing profile, signing job, and Lambda code signing configuration are correctly set up.

Verify the signing profile is active:

aws signer list-signing-profiles --query "profiles[].{Name:profileName,Status:status}" --output table

Confirm the signing job completed successfully:

aws signer list-signing-jobs --status Succeeded --query "jobs[0].{JobId:jobId,Status:status,SignedObject:signedObject}" --output table

Verify the Lambda function has code signing enforced:

aws lambda get-function-code-signing-config --function-name <YOUR-FUNCTION-NAME> --query "{CodeSigningConfigArn:CodeSigningConfigArn}" --output table

Each command should return results confirming the resources are active and properly configured. If any command returns empty results, review the Terraform output for errors during deployment.

Cleaning Up

To avoid incurring future charges, delete the resources created in this walkthrough using the command:

terraform destroy

This command removes all resources including the Lambda function, S3 bucket, VPC components, and KMS keys. This command also deletes the signing profile and code signing configuration.

Conclusion

In this post, you learned how to implement AWS Lambda code signing using Terraform to create a secure, automated deployment pipeline. This solution ensures code integrity, prevents unauthorized modifications, and helps meet compliance requirements while maintaining operational efficiency through infrastructure as code.

The implementation demonstrates defense-in-depth security practices including cryptographic signing, encryption at rest, network isolation, and comprehensive monitoring. By automating the entire process with Terraform, you can consistently deploy secure Lambda functions across multiple environments and maintain security standards at scale.

For more information about AWS Lambda security best practices, see the AWS Lambda Developer Guide. To learn more about AWS Signer, visit the AWS Signer Developer Guide.
About the authors

Sourav Kundu

Sourav is a seasoned DevOps Consultant who specializes in helping organizations securely migrate to and efficiently build on the AWS cloud using modern software engineering practices. He believes that democratizing cloud knowledge is essential for driving innovation and is committed to helping others succeed in their cloud journey.

Joyson Neville Lewis

Joyson is a Sr. Conversational AI Architect with AWS Professional Services. Joyson worked as a Software/Data engineer before diving into the Conversational AI and Industrial IoT space. He assists AWS customers to materialize AI outcomes using Voice Assistant/Chatbot and IoT solutions.

Regional routing for AWS access portals: Implementing custom vanity domains for IAM Identity Center

Post Syndicated from Georgi Baghdasaryan original https://aws.amazon.com/blogs/security/regional-routing-for-aws-access-portals-implementing-custom-vanity-domains-for-iam-identity-center/

AWS IAM Identity Center provides a web-based access portal that gives your workforce a single place to view their AWS accounts and applications. With the recent launch of IAM Identity Center multi-Region replication, customers can replicate their IAM Identity Center instance across multiple AWS Regions to improve resilience and reduce latency for a globally distributed workforce. As a result, users have a dedicated access portal URL in each Region where Identity Center is replicated, and where administrators need a consistent way to manage these portals to ensure that each user reaches the right one.

This post walks you through building a custom vanity domain (for example, aws.mycompany.com) that serves as a single, memorable entry point for access to IAM Identity Center through the AWS Management Console. The solution uses latency-based routing to automatically redirect users to their nearest healthy access portal endpoint and provides a mechanism to trigger failovers when a Regional Identity Center instance, or the broader AWS Region, is impaired. Because this solution operates outside of Identity Center—at the DNS and load balancer layer—users are transparently redirected to the appropriate Regional access portal URL. Note that the vanity domain itself will not appear in the browser’s address bar.

This guide is structured in three progressive phases: a single-Region redirect, multi-Region latency routing, and automatic health-based failover. You can adopt each phase independently, depending on your organization’s needs.

Note: While this guide focuses on IAM Identity Center access portal endpoints, the same approach using Amazon Route 53 latency-based routing, Application Load Balancer (ALB) redirects, and Amazon Application Recovery Controller (ARC) Region switch can be applied to build a custom vanity domain and intelligent routing layer for any other HTTP endpoint type.

Background

IAM Identity Center supports multiple access portal URL formats that resolve to the same web portal. The following table summarizes the supported formats in the standard AWS (classic) partition, along with their capabilities:

Format IPv4 Dual-stack Multi-Region* Example
https://{directoryId}.awsapps.com/start Yes No No https://d-1234567890.awsapps.com/start
https://{alias}.awsapps.com/start Yes No No https://mycompany.awsapps.com/start
https://{idcInstanceId}.{region}.portal.amazonaws.com Yes No Yes https://ssoins-1234567890.us-west-2.portal.amazonaws.com
https://{idcInstanceId}.portal.{region}.app.aws ★ Yes Yes Yes https://ssoins-1234567890.portal.us-west-2.app.aws

* Each Regional URL resolves only to its own Region’s portal instance and doesn’t fail over to another Region. Multi-Region here means the URL format is available in every Region where IAM Identity Center is replicated. To route users across Regions dynamically, use the vanity domain approach described in this post.

Note: The ★ highlighted row (https://{idcInstanceId}.portal.{region}.app.aws) is the recommended URL format. It supports both dual-stack (IPv4 and IPv6) and IAM Identity Center multi-Region replication. The awsapps.com formats aren’t always available in newer Regions and don’t support multi-Region capabilities. In additional replicated Regions, the custom alias isn’t supported, and the awsapps.com parent domain isn’t available.

Working with multiple Regional endpoints

As you expand your IAM Identity Center footprint through multi-Region replication, each replicated Region provides a dedicated access portal URL—directing your users to the low-latency entry point closest to their location. A user connecting from Europe and one connecting from Asia Pacific each benefit from their respective Regional endpoint. To deliver the best experience, organizations need a consistent, centrally managed way to direct users to the correct Regional destination; there are a few common approaches you can use to achieve this.

Customers typically start with a single Regional endpoint, which is straightforward to configure, but users in distant Regions experience higher latency, and a Regional incident can affect all users regardless of location. Others maintain per-Region bookmarks or configuration, which gives each user population the right endpoint but requires ongoing IT coordination and clear communication to users.

Custom vanity domains give you full control over DNS routing, health checks, and failover of your access portal connections; all behind a single, brand-aligned domain name (for example, aws.mycompany.com) that users access. A vanity domain makes this start URL memorable and consistent for users, regardless of the underlying IAM Identity Center configuration – a single address to remember and share, compared to maintaining a separate bookmark for each Regional endpoint or managing a growing list of application tiles in your external identity provider. The rest of this guide walks you through how to deploy this solution step by step.

Solution overview

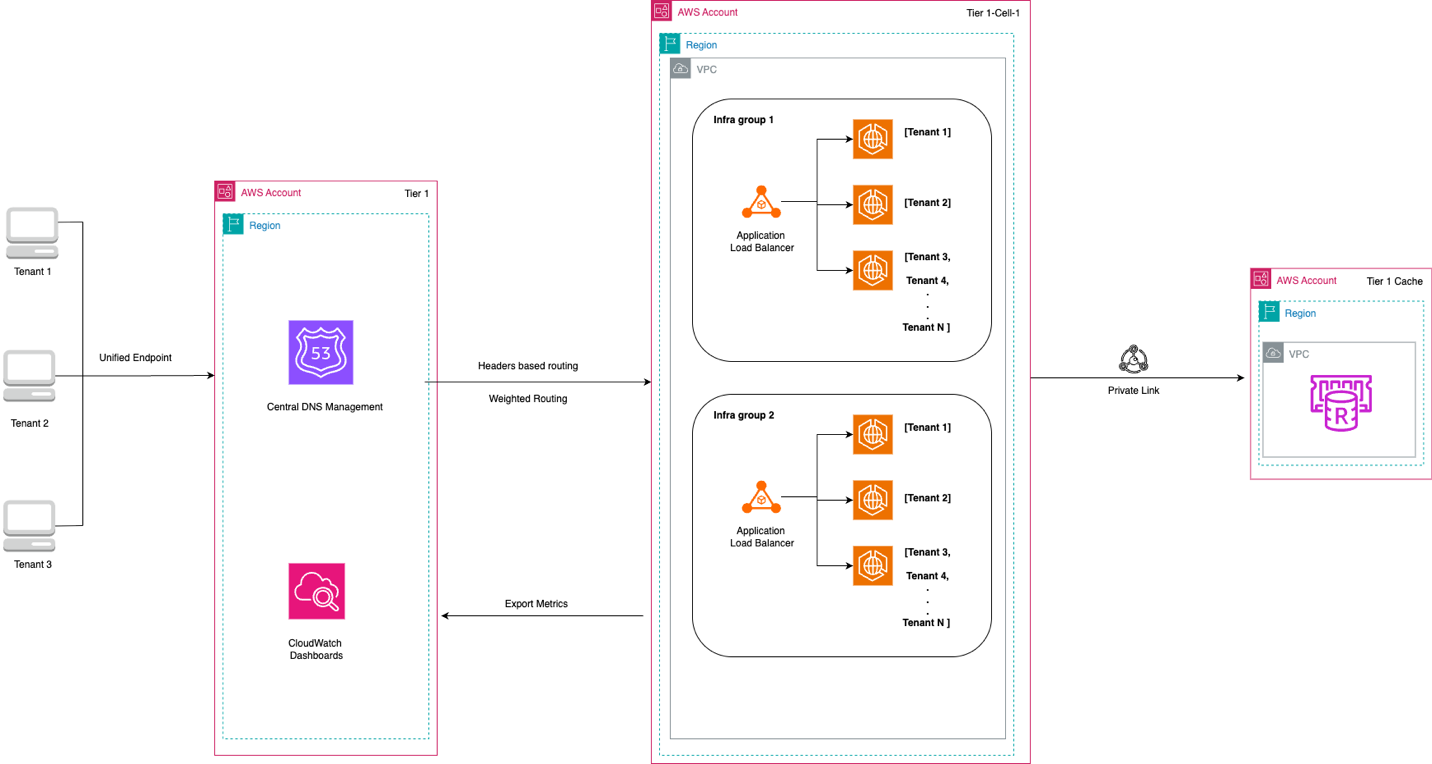
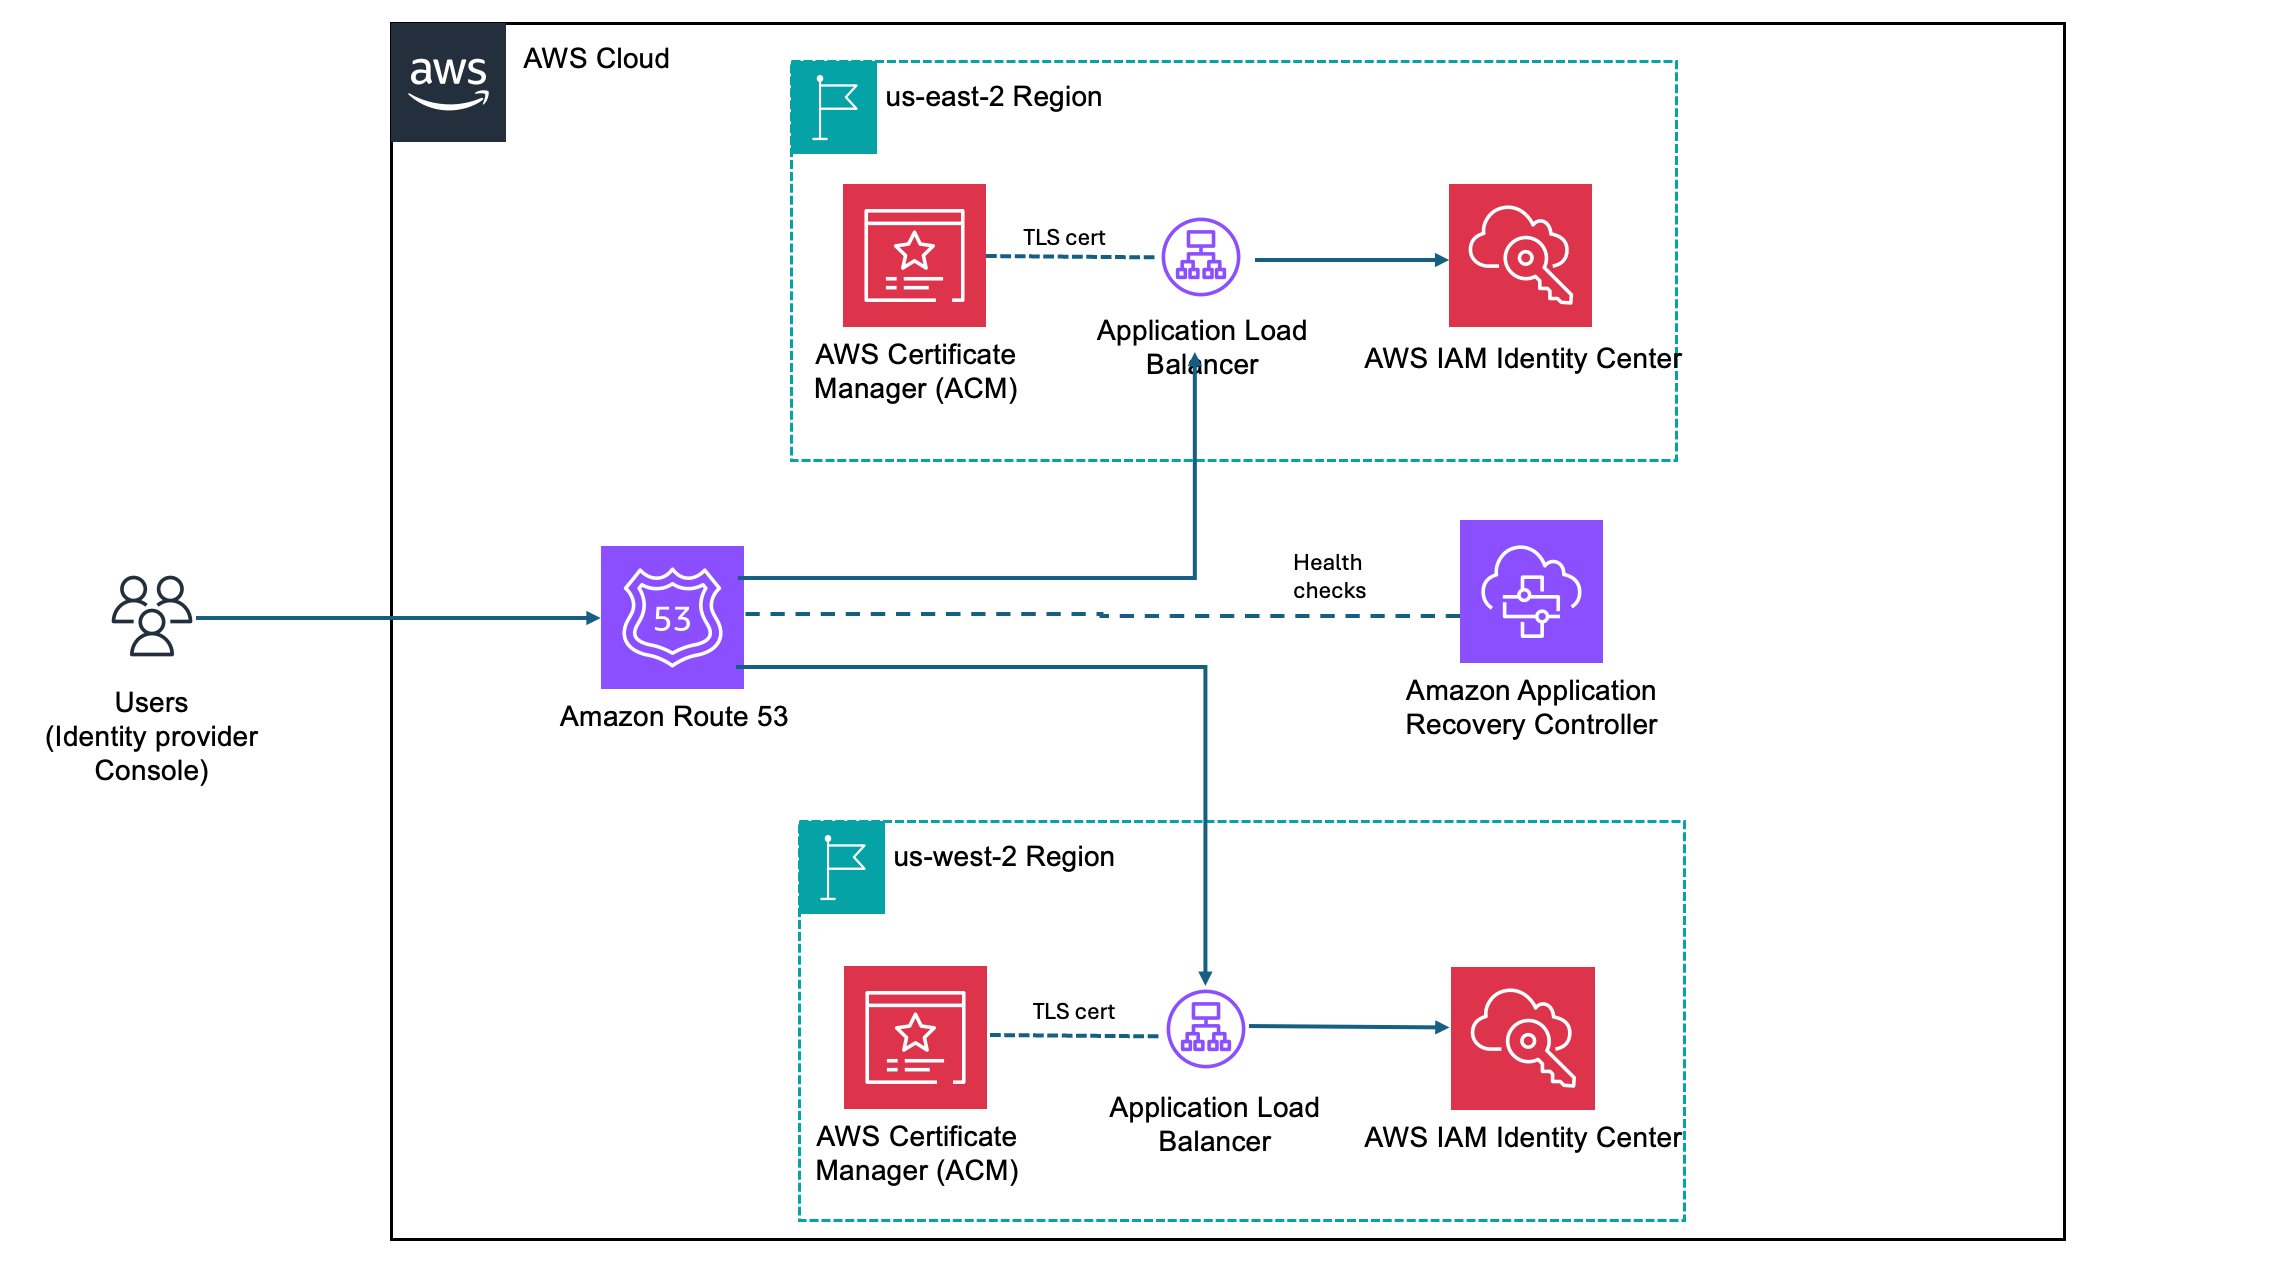
The solution builds a lightweight routing and redirect layer in front of the IAM Identity Center access portal Regional endpoints. The architecture has the following components:

  • AWS IAM Identity Center – Your existing Identity Center instance
  • Amazon Route 53 – Manages your vanity domain’s hosted zone, latency-based routing policy, and health checks
  • AWS Certificate Manager (ACM) – Issues and automatically renews TLS certificates for your vanity domain in each Region
  • Application Load Balancer (ALB) – Handles HTTP and HTTPS traffic, issuing 302 redirects to the appropriate Regional access portal endpoint
  • Amazon Application Recovery Controller (ARC) Region switch – Orchestrates Regional failovers by controlling Route 53 health check states, so traffic is automatically shifted away from an unhealthy Region

This guide is structured in three progressive phases. You can adopt each phase incrementally based on your needs:

  • Phase 1: Sets up the vanity domain with a redirect to a single Regional access portal endpoint. Suitable for organizations with a single-Region Identity Center deployment.
  • Phase 2: Extends Phase 1 across multiple Regions with latency-based routing, so users are automatically directed to the nearest Regional endpoint. Requires IAM Identity Center multi-Region replication.
  • Phase 3: Adds an ARC Region switch for managed Regional failover. Without Phase 3, a Regional impairment requires manual DNS updates to redirect traffic. ARC automates this with rehearsable, controlled failover plans.

Figure 1: Solution architecture for custom vanity domain routing with IAM Identity Center.

When a user navigates to aws.mycompany.com, the following happens:

  1. Route 53 evaluates the latency records and routes traffic to the ALB in the lowest-latency healthy Region.
  2. The ALB terminates TLS using an ACM-managed certificate and issues a 302 redirect to the corresponding Regional Identity Center access portal URL.
  3. The user’s browser follows the redirect and loads the access portal directly. Subsequent authentication traffic flows between the browser and AWS—the ALB isn’t in the path.

If you’ve implemented Phase 3, ARC controls Route 53 health check states for each Region. With this configuration, you can stop routing traffic to any Region considered unhealthy.

Prerequisites

Before you begin to build the solution, ensure you have the following in place:

  1. An existing top-level domain (TLD) (for example, mycompany.com).
  2. An AWS IAM Identity Center organization instance configured.
  3. For Phases 2 and 3, you need IAM Identity Center multi-Region replication configured with at least two Regions. See Setting up IAM Identity Center multi-Region replication for instructions.
  4. AWS Identity and Access Management (IAM) permissions on a dedicated networking or shared services account in your organization to manage Route 53, ACM, Amazon Elastic Compute Cloud (Amazon EC2), ALB (phase 1 and 2), and ARC (phase 3).

Phase 1: Redirect to a single predefined access portal endpoint

In this phase, you create the foundational infrastructure: a Route 53 hosted zone, an ACM-managed TLS certificate, and an internet-facing ALB that issues a 302 redirect to your Regional access portal URL. By the end, users who navigate to aws.mycompany.com will be seamlessly redirected to your Identity Center portal.

Create a Route 53 hosted zone for your vanity domain

The hosted zone holds the DNS records that control how aws.mycompany.com resolves. If your top-level domain (mycompany.com) is already registered in Route 53, you create a subdomain hosted zone. If it’s registered with another registrar, you create a public hosted zone and configure name server (NS) delegation manually.

  1. In the AWS Management Console, navigate to Route 53 and choose Hosted zones, then Create hosted zone.
  2. Enter your vanity domain in the Domain name field (for example, aws.mycompany.com).
  3. Select Public hosted zone as the type, then choose Create hosted zone.
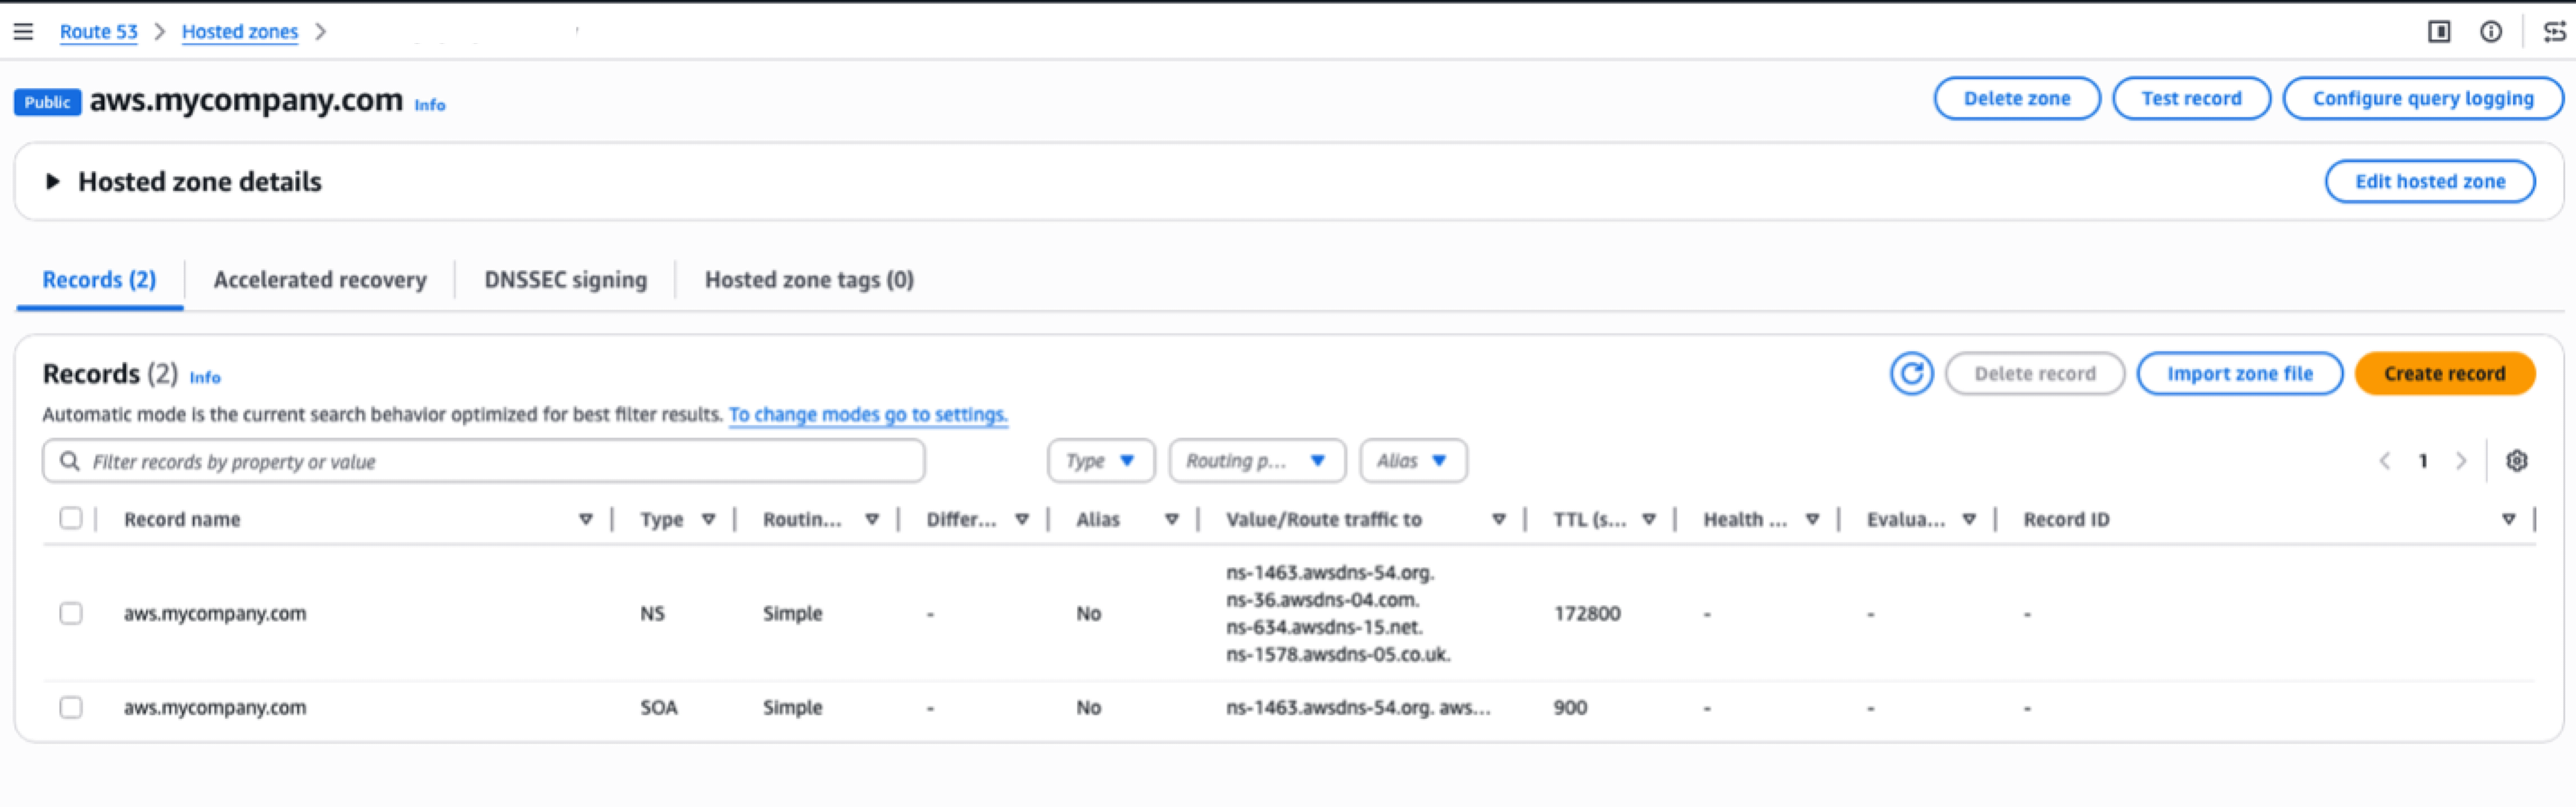
  4. Note the four NS records that Route 53 creates for the new hosted zone. You will need these in the next step.

Figure 2: Route 53 hosted zone details

Delegate your subdomain from the parent domain

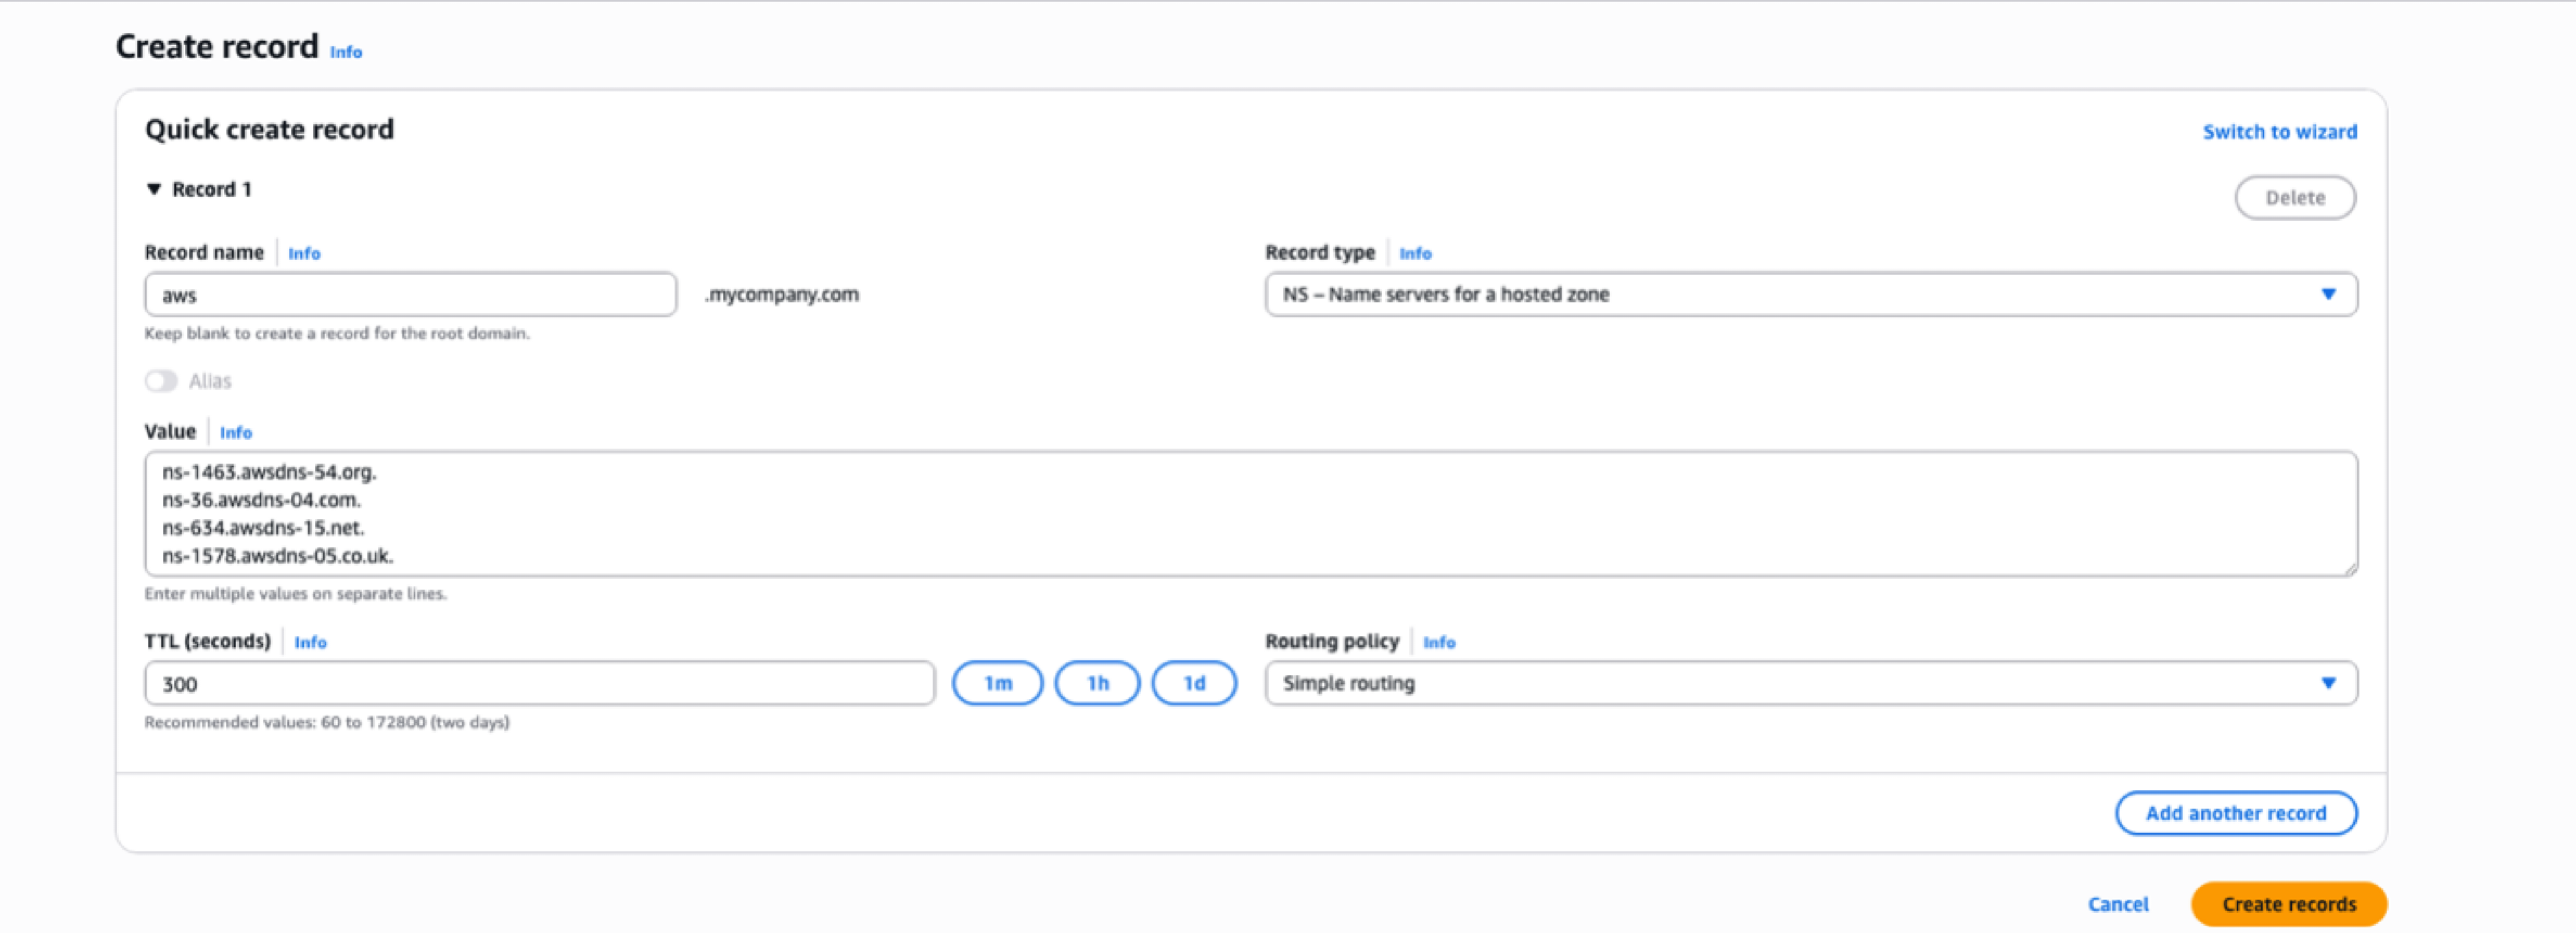
To make Route 53 authoritative for aws.mycompany.com, you must add an NS record in the parent zone (mycompany.com) pointing to the name servers of the new hosted zone.

  • If mycompany.com is hosted in Route 53: Open the mycompany.com hosted zone, choose Create record, set the record name to aws, the type to NS, and paste the four NS values from the previous step. Choose Create records.
  • If mycompany.com is hosted elsewhere: Sign in to your registrar’s DNS management console and add an NS record for aws.mycompany.com using the four name server values from the previous step.

Note: DNS propagation for NS delegation can take up to 48 hours, though it typically completes within a few minutes for Route 53-to-Route 53 delegation.

Figure 3: Create a NS record type to delegate your subdomain from the parent domain

Request an ACM certificate

Your ALB requires a TLS certificate for aws.mycompany.com to serve HTTPS traffic. ACM provides free public certificates with automatic renewal.

  1. Go to the Certificate Manager console in the primary Region of IAM Identity Center (for example, us-east-2) and choose Request a certificate.
  2. Select Request a public certificate and choose Next.
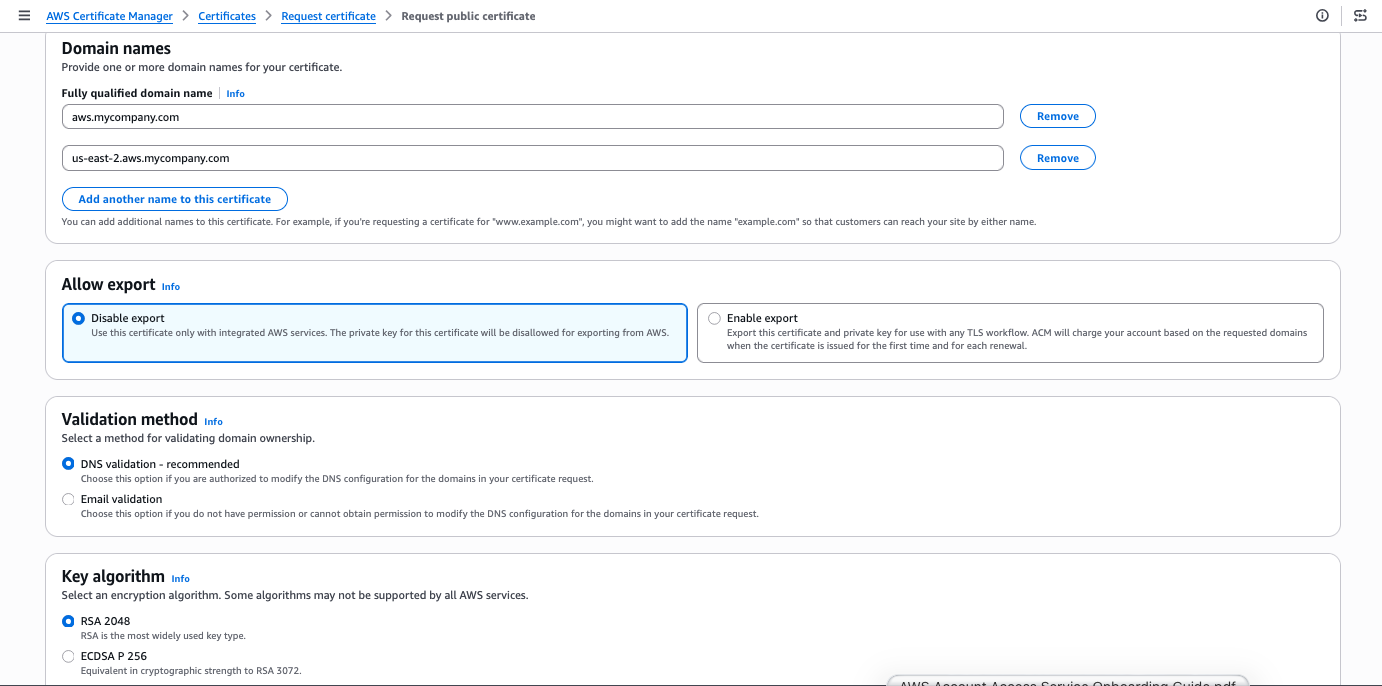
  3. Enter your domain name (for example, aws.mycompany.com). Choose Add another name to this certificate and enter your Regional sub-domain (for example, us-east-2.aws.mycompany.com).
  4. Leave other options as defaults (Disable export, DNS validation – recommended, and key algorithm – RSA 2048) and choose Request.
  5. In the certificate details page, choose Create records in Route 53. ACM will automatically add the validation CNAME records to your hosted zone. The certificate status changes to Issued within a few minutes.

Figure 4: Request an ACM certificate for your domain

Create a security group for Identity Center ALB

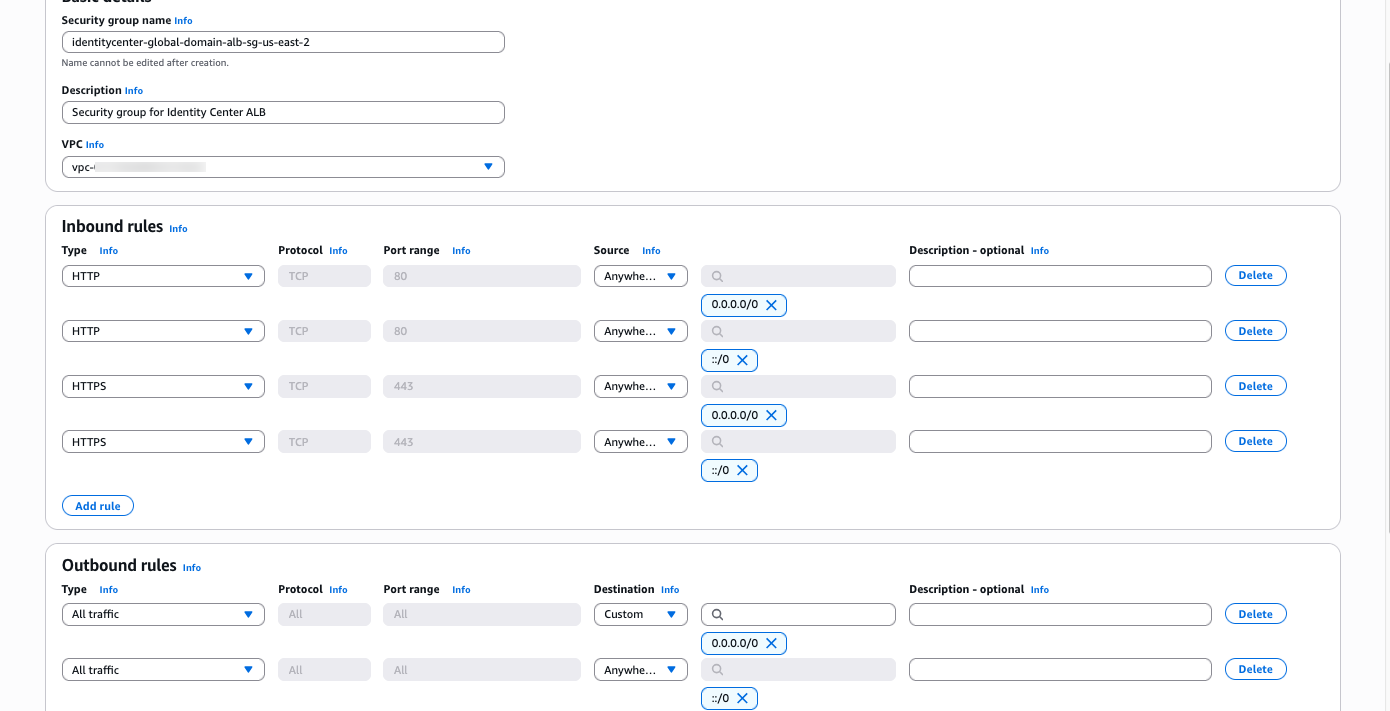
The security group needs to allow inbound HTTP and HTTPS traffic for both IPv4 and IPv6 from the public internet to make the load balancer reachable.

  1. Go to the Amazon EC2 console, navigate to Security Groups, and choose Create security group.
  2. Enter a Name (for example, identitycenter-global-domain-alb-sg-us-east-2) and Description. Add four rules by choosing Add Rule under Inbound Rules.
    1. Set Type to HTTP, and Source to Anywhere-IPv4 (0.0.0.0/0) and to Anywhere-IPv6 (::/0).
    2. Set Type to HTTPS, and Source to Anywhere-IPv4 (0.0.0.0/0) and to Anywhere-IPv6 (::/0).
  3. Choose Add Rule under Outbound Rules and set Type to All traffic and Source to Anywhere-IPv6 (::/0).
  4. Choose Create security group.

Figure 5: ALB security group rules

Create an ALB with an HTTP and HTTPS redirect rule

The ALB is the component that performs the actual redirect to your IAM Identity Center access portal URL. The ALB listener accepts HTTPS requests on port 443 and responds with a 302 redirect to the appropriate Regional Identity Center access portal endpoint.

  1. Go to the Amazon EC2 console, navigate to Load Balancers, and choose Create load balancer. Select Application Load Balancer.
  2. Enter a name for your ALB (for example, identitycenter-redirect-alb).
  3. Configure basic settings: Set the scheme to Internet-facing, IP address type to Dualstack (or IPv4 if IPv6 isn’t supported by your virtual private cloud (VPC)), and select at least two Availability Zones. Ensure that the load balancer is operating in a VPC and subnets that are internet-facing.
  4. Under Security Groups choose the Security Group created in the previous step.
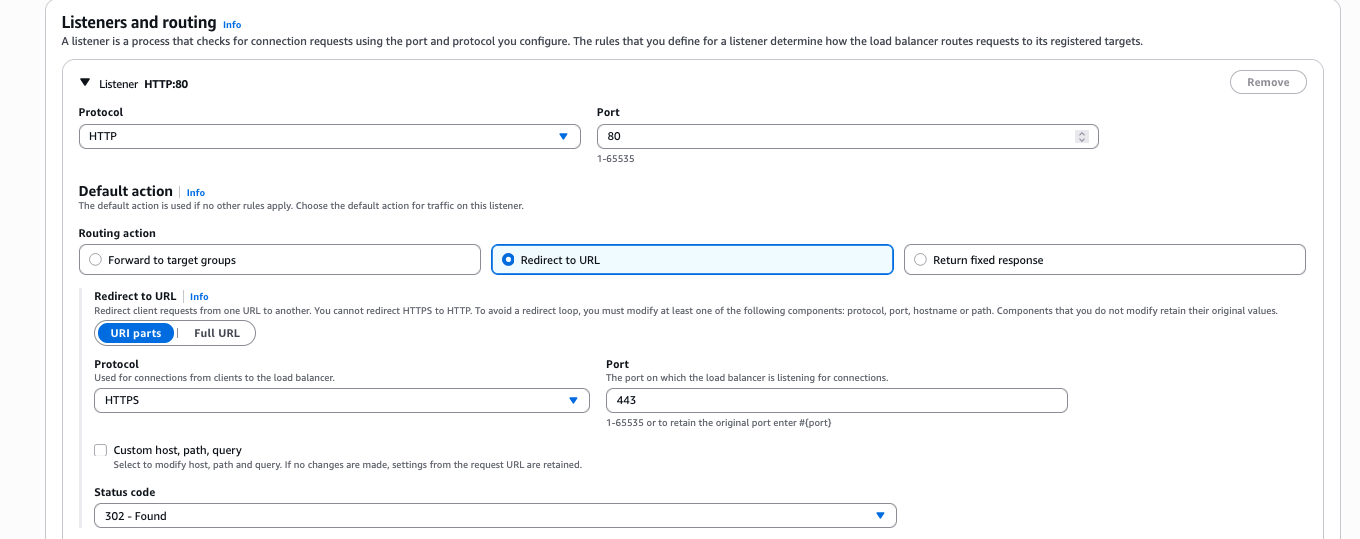
  5. Configure an HTTP listener: Add a listener on port 80 (HTTP) with Redirect to URL option. Choose URL parts and set Protocol to HTTPS, Port to 443, and status code to 302 (Found).

    Figure 6: Add an HTTP listener during ALB creation

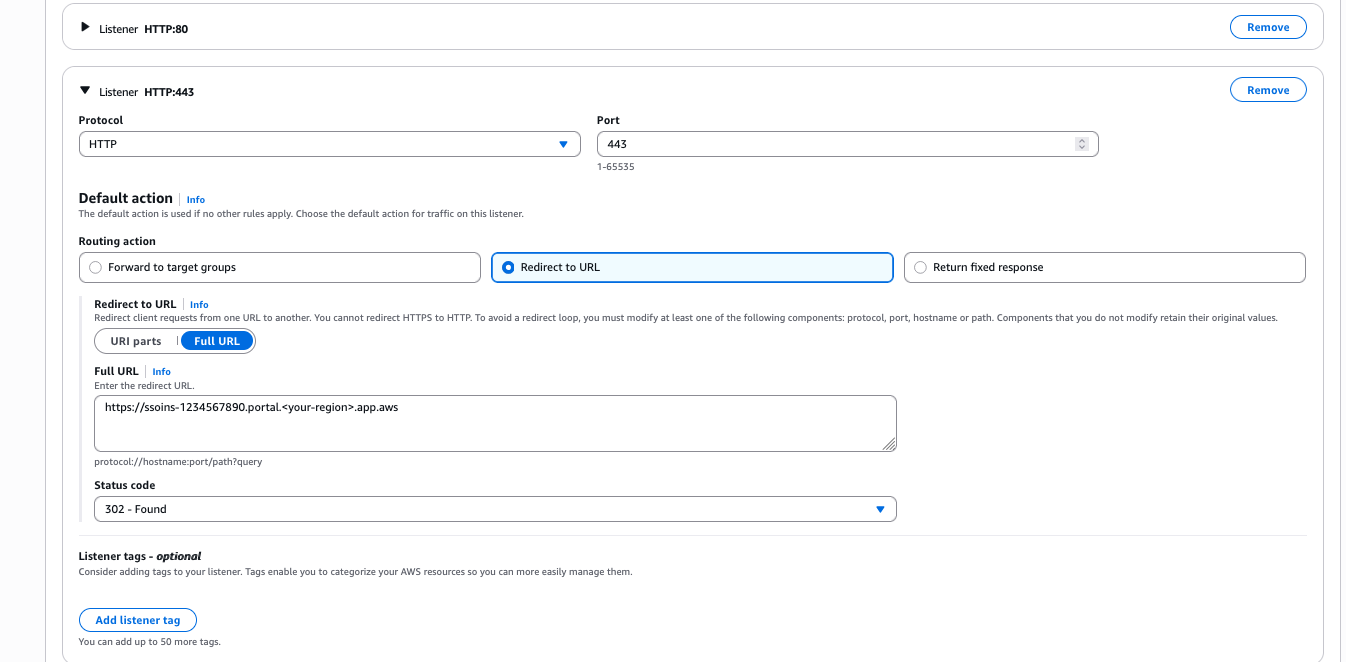
  6. Configure an HTTPS listener: Add a listener on port 443 (HTTPS) with No pre-routing action (default) and Redirect to URL options. Choose Full URL and set the URL to your Regional Identity Center access portal endpoint (For example, https://ssoins-1234567890.portal.<your-region>.app.aws, for this blog the region is us-east-1). Set status code to 302 (Found).

    Figure 7: Add an HTTPS listener

  7. Under Default SSL/TLS certificate, select the ACM certificate you created in Step 3.

    Note: Make sure to select 302 – Found as the Status code. Selecting 301 – Permanently moved will result in browser caching the redirect URL which will prevent failovers from working correctly until the cache expires.

Create Regional Route 53 records pointing to your ALB

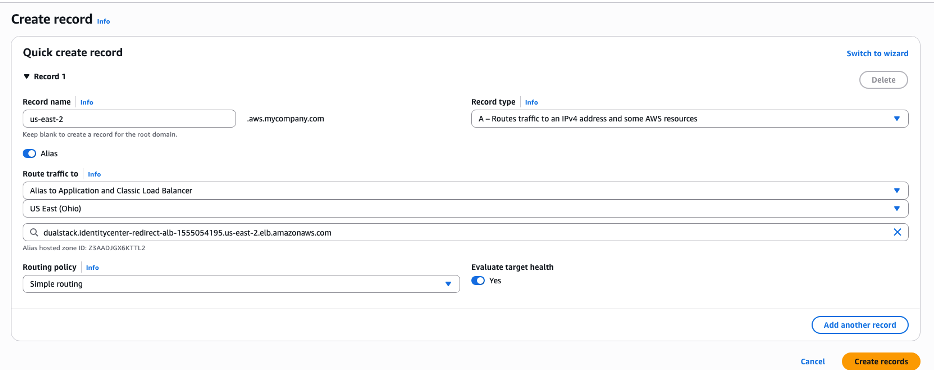
Create a DNS record in your hosted zone that resolves <your-region>.aws.mycompany.com to your ALB.

  1. Open your Route 53 hosted zone for aws.mycompany.com and choose Create record.
  2. Set the record name to the AWS Region name (For example: us-east-2) and the record type to A.
  3. Toggle Alias and in the drop down menu Route traffic to, select the alias target to Alias to Application and Classic Load Balancer, select your Region (For example:us-east-2), and select your ALB from the dropdown list.
  4. Leave routing policy as Simple routing, and select the Region (For example:us-east-2) and choose Create records.
  5. Repeat steps 1 through 4 to create AAAA record types.

Figure 8: Route 53 record with simple routing policy

Add latency-based routing configurations

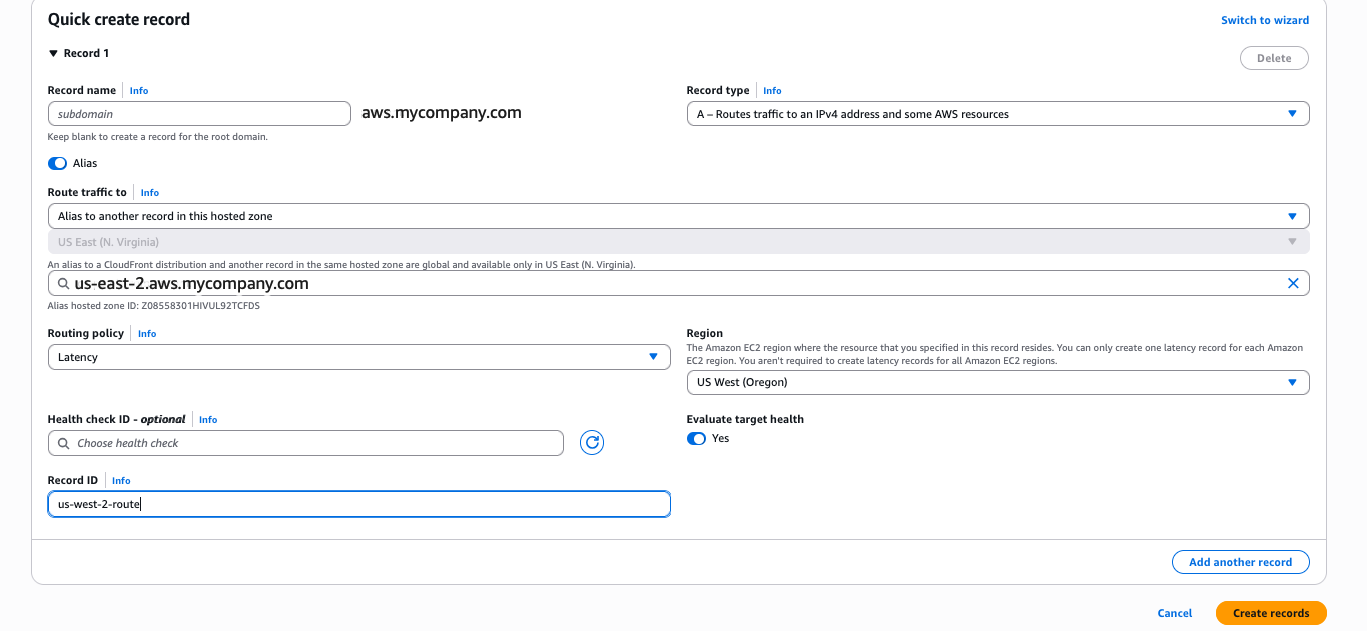
Finally, create a DNS record in your hosted zone that resolves aws.mycompany.com to your Regional Route 53 record.

  1. Open your Route 53 hosted zone for aws.mycompany.com and choose Create record.
  2. Keep the subdomain name for this record as empty, so aws.mycompany.com is the fully qualified record and set the record type to A.
  3. Enable alias: Set the Route traffic to Alias to another record in this hosted zone, and select the hosted zone you created earlier (us-east-2.aws.mycompany.com).
  4. Set Routing Policy to Latency and select the corresponding Region (us-east-2 in this example).
  5. Add a clear name for the Record ID, such as us-east-2--ipv4 as a differentiator and choose Create records.
  6. Repeat the steps 1 through 5 to create AAAA record types with us-east-2--ipv6 as the record ID.
Figure 9: Route 53 record with latency-based routing

Figure 9: Route 53 record with latency-based routing

Test the configuration by navigating to https://aws.mycompany.com in a browser. You should be redirected to your Identity Center access portal. You can also validate using:
curl -I https://aws.mycompany.com

Expected response:

HTTP/2 302

location: https://ssoins-1234567890.portal.<your-region>.app.aws

Tip: To deploy Phase 1 automatically, download the CloudFormation template from the Deploying with CloudFormation section below.

Phase 2: Automatically route to the nearest Regional access portal endpoint

Phase 2 extends the solution to support IAM Identity Center multi-Region replication by deploying an ALB in each replicated Region and configuring Route 53 latency-based routing. Users are automatically directed to the access portal in the Region that has the lowest network latency from their location, which matches the active-active behavior of the Identity Center access portal itself.

Request ACM certificates in each additional Region

Repeat the steps from Request an ACM Certificate for each additional Region (for example, us-west-2) where you’ve replicated IAM Identity Center.

Create a security group and an ALB in each additional Region

Repeat the steps from Create a security group for Identity Center ALB and Create an ALB with an HTTP and HTTPS redirect rule in each additional Region. In each ALB’s redirect rule, set the target URL to the access portal endpoint for that specific Region. For example:

  • us-east-2 ALB redirects to https://ssoins-1234567890.portal.us-east-2.app.aws
  • us-west-2 ALB redirects to https://ssoins-1234567890.portal.us.west-2.app.aws

Create Regional and latency Route 53 records for the additional Region

For each additional Region where you’ve deployed an ALB and replicated Identity Center, create Regional and latency A and AAAA records as outlined in Create Regional Route 53 records pointing to your ALB and Add latency-based routing configurations.

Tip: To deploy Phase 2 automatically, download the CloudFormation template from the following Deploying with CloudFormation section.

Phase 3: Regional failover using ARC Region switch

Phase 3 introduces Amazon Application Recovery Controller (ARC) Region switch, a fully managed capability that you can use to plan, practice, and orchestrate Regional failovers with confidence. ARC Region switch vends Route 53 health checks directly as part of a Region switch plan. You attach these generated health checks to your Route 53 latency records, and ARC controls their healthy or unhealthy state during plan execution. You can further extend the solution to include custom automation triggered by Amazon CloudWatch alarms or synthetic canaries to update routing control state.

We recommend creating your ARC Region switch plan in the primary Region of your IAM Identity Center for ease of discovery.

Create an active-active instance of ARC Region switch plan

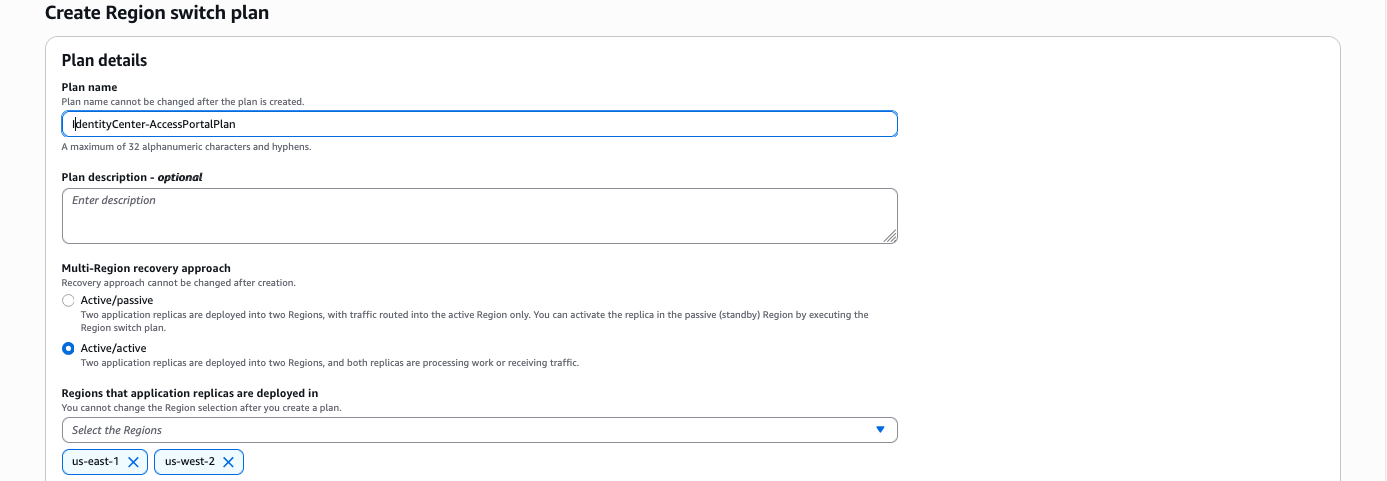
Create an ARC Region switch plan that will orchestrate failovers between your IAM Identity Center Regions and auto-generate the Route 53 health checks you will reference in the next step.

  1. Open the Application Recovery Controller console and choose Region switch in the navigation pane. Select Create Region Switch Plan.
  2. Enter a Plan name (for example, idc-access-portal-failover) and an optional description. Choose Active/Active for Multi-Region recovery approach. Select the Regions where IAM Identity Center is replicated ,including the primary Region.
  3. In the Execution Permission section, enter the Amazon Resource Name (ARN) of the IAM role that ARC will use to update Route 53 health check states during plan execution. If you don’t have an existing role, choose Create a new role to have ARC create one automatically. See AWS Managed Policy: AmazonApplicationRecoveryControllerRegionSwitchPlanExecutionPolicy for information about required permissions.
  4. Choose Create Plan and proceed to Build workflows. Enter optional descriptions and choose Save and continue.

    Figure 10: Region switch plan

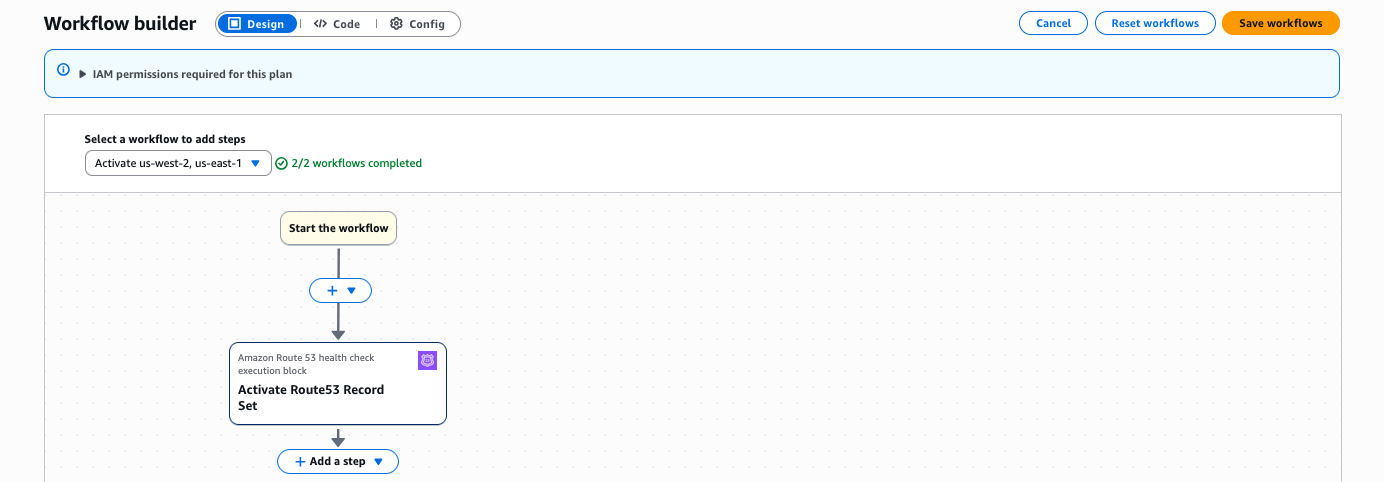
  5. Set the Workflow type to Activate and set the Region to the corresponding Region (us-east-2 or us-west-2). Within each workflow, choose Add step/Run in Sequence. Choose an execution block to Amazon Route 53 health check execution blog under Networking.
  6. Choose Add and edit. Enter a Step name (for example, Activate Route53 Record Set).
  7. Set the Hosted zone to the hosted zone ID for your aws.mycompany.com domain, and set the Record name to aws.mycompany.com.
  8. Expand Record set identifiers. Choose Add record set identifier and enter a unique identifier for the record set (for example, us-east-2--ipv4 and us-east2--ipv6) and select your Region. Add two record set identifiers (A and AAAA records) for each of your Regions.
  9. Choose Save step.
  10. Repeat steps 5 and 6 for Deactivate and choose Save the plan.

    Figure 11: Workflow builder

  11. Choose Save workflows.
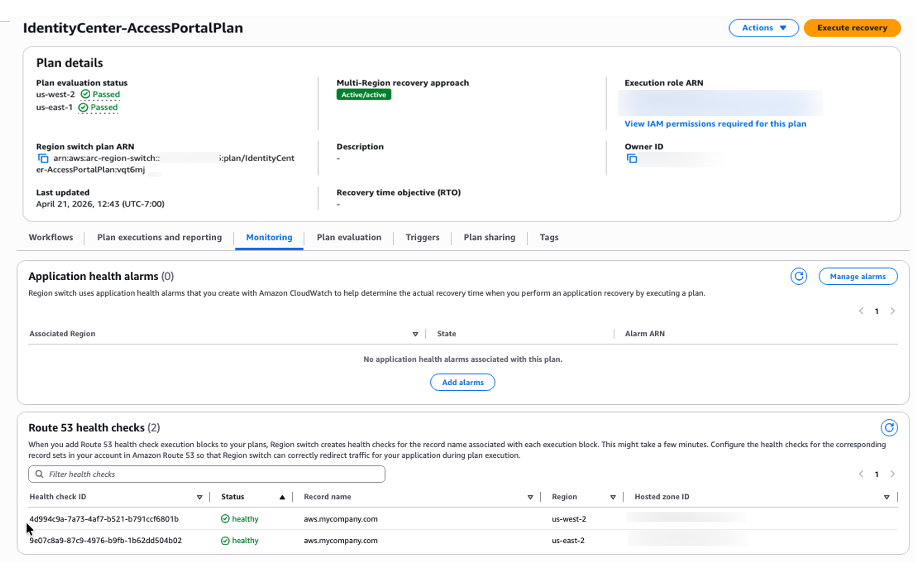
  12. Select the newly created plan and choose the Monitoring tab. Note the IDs of the health checks created.

    Figure 12: IAM Identity Center access portal plan

Update Route 53 record sets to reference ARC-managed health checks

Associate the ARC-generated health check IDs with the latency-based A and AAAA records you created in Phase 1 and 2. Route 53 uses these health checks—which are now controlled by ARC—to determine which Regions are eligible for DNS resolution. Route 53 still uses latency to choose from the healthy Regions.

    1. Go to the Route 53 console and choose Hosted zones.
    2. Select the hosted zone for aws.mycompany.com.
    3. Find the latency-based A record for us-east-2 that you created in Phase 2, and choose Edit record.
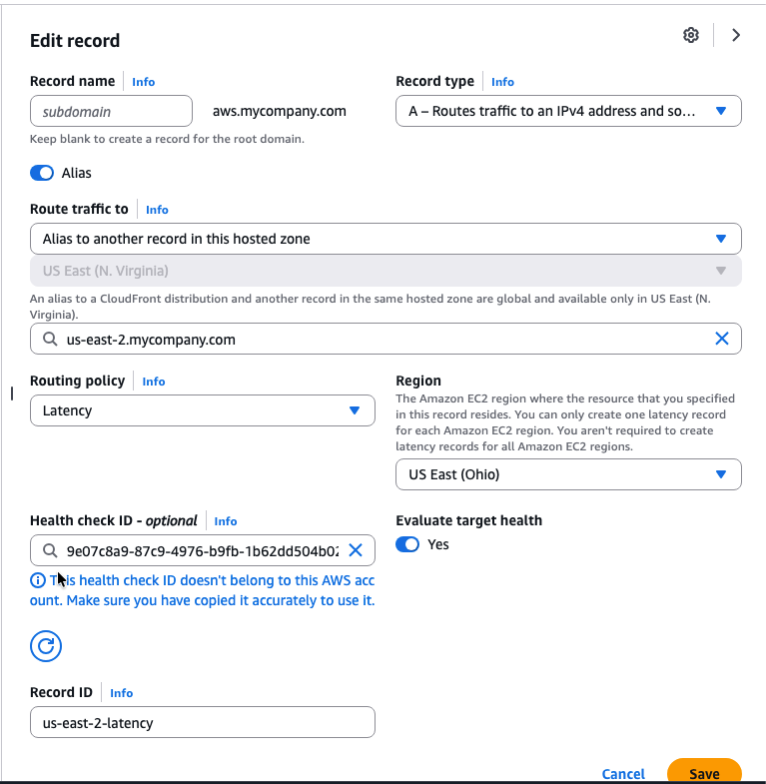
    4. In the Health check section, enable Associate with a health check. In the Health check ID dropdown, select the ARC-generated health check for us-east-2 that you noted at the end of the preceding procedure. Note: Ignore the warning This health check ID doesn’t belong to this AWS account. Make sure you have copied it accurately to use it.
    5. Choose Save changes.
    6. Repeat steps 3, 4, and 5 for A and AAAA records for each of your IAM Identity Center Regions.

Figure 13: Update Route53 record sets

Validate the setup by performing a failover

Validate the end-to-end configuration by executing a controlled failover. Because latency-based routing will always resolve aws.mycompany.com to us-east-2 for users in the primary geography, deactivating us-east-2 is the most direct way to confirm that Route 53 correctly fails over to us-west-2.

    1. Before executing the failover, confirm that aws.mycompany.com is resolving to the us-east-2:
      curl -I https://aws.mycompany.com
      Expected: A record pointing to the us-east-2 access portal URL (for example, https://ssoins-1234567890.portal.us-east-2.app.aws:443/).
    2. Go to the Amazon Application Recovery Controller console. In the left navigation pane, choose Region switch.
    3. Select your Region switch plan (idc-access-portal-failover) to open the plan details page.
    4. Choose Execute recovery.
    5. On the Execute plan page, select us-east-2 as the Region to fail out of.
    6. Select the Deactivate action and choose Start execution. ARC sets the us-east-2 health check to unhealthy. Route 53 stops resolving aws.mycompany.com to the us-east-2 ALB and routes traffic to us-west-2 instead.
    7. After a few seconds, confirm the failover has taken effect:
      curl -I https://aws.mycompany.com
      Expected: 302 redirect to the us-west-2 IAM Identity Center access portal URL
    8. To fail back, choose Execute plan again. Select us-east-2, select the Activate action and choose Start execution. ARC marks the us-east-2 health check healthy and Route 53 resumes routing traffic to that Region.

Tip: To deploy Phase 3 automatically, download the CloudFormation template from the Deploying with CloudFormation section that follows.

Deploying with CloudFormation

As an alternative to the manual console steps described previously, we provide CloudFormation templates that you can download and deploy for each phase. Each template is self-contained and parameterized, so you only need to provide your environment-specific values (such as your vanity domain name, VPC, and subnet IDs). Download the templates from the following links:

To deploy a template, navigate to the AWS CloudFormation console, choose Create stack, select Upload a template file, and upload the downloaded YAML file. Follow the prompts to provide parameter values and create the stack. For Phase 2, deploy the template once in each additional Region.

Deploy all phases with a single scrip

As an alternative to deploying each CloudFormation template individually, you can use the provided deploy.sh bash script to deploy all three phases in sequence. The script automates stack creation across your primary and additional Region. To get started, download the deployment package, then unzip the file into a local directory:

wget https://aws-security-blog-content.s3.us-east-1.amazonaws.com/public/sample/3536-regional-routing-for-aws-access-portals/Vanity-domains-cfn.zip
unzip  Vanity-domains-cfn.zip
cd Vanity-domains-cfn

Before running the script, open the deploy.sh file and update the following required parameters with your environment-specific values:

  • TLD – Your top-level domain (for example, mycompany.com)
  • TLD_HOSTED_ZONE_ID – The Route 53 hosted zone ID for your top-level domain
  • IDC_SUBDOMAIN – The Identity Center subdomain name (for example, aws)
  • IDC_INSTANCE_ID – Your IAM Identity Center instance ID (for example, ssoins-1234567890)
  • PRIMARY_REGION – The primary Region for your Identity Center instance (for example, us-east-2)
  • ADDITIONAL_REGIONS – The additional Region for multi-Region replication (for example, us-west-2)

After updating the configuration, run the deployment script:

./deploy.sh

The script deploys Phase 1 (single-Region redirect), Phase 2 (multi-Region latency-based routing), and Phase 3 (ARC Region switch failover) in order. Monitor the terminal output for stack creation progress and any errors.

After completing the setup, you can integrate the vanity URL (for example, aws.mycompany.com) directly into your identity provider, such as Okta or Microsoft Entra ID, as a bookmark application or a chiclet URL. By configuring the vanity URL as the bookmark target, users who launch the application from their identity provider dashboard are always redirected to the nearest IAM Identity Center access portal endpoint through latency-based routing. If a Regional impairment occurs and a failover is necessary, administrators can execute an ARC Region switch to deactivate the impaired Region, and users will automatically be redirected to the active Identity Center endpoint without any change to the bookmark URL or end-user experience.

Conclusion

In this post, you learned how to build a custom vanity domain for an AWS IAM Identity Center access portal using Amazon Route 53, AWS Certificate Manager, Application Load Balancer, and an Amazon Application Recovery Controller (ARC) Region switch. The three-phase approach lets you start with a single-Region redirect, progressively add latency-based routing as your IAM Identity Center footprint grows with multi-Region replication, and then introduce an ARC Region switch to gain fully managed, rehearsable Regional failover.

For more information about IAM Identity Center multi-Region replication, see the IAM Identity Center User Guide. For more resilience patterns, visit the AWS Architecture Blog posts about Resilience. If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Resources


Georgi Baghdasaryan

Georgi Baghdasaryan

Georgi is a Principal Engineer at Amazon Web Services, where he builds identity systems that help organizations securely manage access and authentication at scale. His broader focus is on reliable, high-impact infrastructure that enables customers to operate confidently in the cloud. Outside of work, Georgi enjoys experimenting with new matcha latte recipes and going on long bike rides.

Sowjanya Rajavaram

Sowjanya Rajavaram

Sowjanya is a Sr Solutions Architect who specializes in Identity and Security in AWS. She works on helping customers of all sizes solve their identity and access management problems. She enjoys traveling and exploring new cultures and food.

Author

Laura Reith

Laura is an Identity Solutions Architect at AWS, where she thrives on helping customers overcome security and identity challenges. In her free time, she enjoys wreck diving and traveling around the world.

Automating post-quantum cryptography readiness using AWS Config

Post Syndicated from Pravin Nair original https://aws.amazon.com/blogs/security/automating-post-quantum-cryptography-readiness-using-aws-config/

Migrating your TLS endpoints to Post-quantum cryptography (PQC) starts with understanding your current TLS endpoint inventory and posture. This post introduces the PQC Readiness Scanner — an automated tool that inventories your Application Load Balancer (ALB), Network Load Balancer (NLB), and Amazon API Gateway endpoints and continuously monitors their TLS configurations for PQC readiness. The scanner classifies each endpoint into a three-tier framework that helps prioritize and plan PQC migration.

As quantum computing advances, you need to migrate to quantum-resistant cryptography to protect your data long-term. The PQC Readiness Scanner helps you identify which endpoints to migrate first and tracks your progress across accounts. For web traffic, PQC key exchange algorithms are negotiated only within TLS 1.3. This means quantum-resistant connections require endpoints that support TLS 1.3 and PQC key exchange.

Under the AWS Shared Responsibility Model, AWS secures the infrastructure and enables PQC support across its services. Customers are responsible for configuring their resources to use PQC-capable TLS policies. For AWS-terminated TLS connections—such as those on Application Load Balancer (ALB), Network Load Balancer (NLB), Amazon API Gateway, and Amazon CloudFront—customers choose the security policy (an AWS-managed configuration defining supported TLS protocol versions and cipher suites for a listener) that determines TLS version and cipher suite, key exchange, and authentication algorithm support.

The automated PQC Readiness Scanner for AWS-terminated TLS endpoints is built using AWS Config conformance packs. A conformance pack is a collection of AWS Config rules and remediation actions that can be deployed as a single entity in an account and a Region or across an organization in AWS Organizations.

Solution overview

The PQC Readiness Scanner deploys AWS Config rules using a conformance pack to evaluate the security policy on each endpoint. Based on the evaluation, each resource is classified into a three-tier readiness framework that prioritizes migration actions needed to achieve PQ-ready TLS.

The PQC Readiness Scanner performs two checks per resource:

  1. Does the endpoint use a PQ-ready security policy?
  2. Does the endpoint support legacy TLS 1.0 or 1.1?

Each check returns COMPLIANT or NON_COMPLIANT status with specific policy recommendations.

PQC requires endpoints to support TLS 1.3 and use PQC key exchange algorithms. The three-tier framework helps you interpret findings and prioritize fixes. The goal is to have TLS 1.3 with PQC key exchange enabled on the endpoints. However, achieving this requires maintaining backward compatibility with clients.

Tier

Readiness level

TLS protocols

PQC status

Migration priority

Tier 1

PQ-ready (strongest posture)

TLS 1.3 only with PQC key exchange

PQ-ready

None

Tier 2

PQ-ready (backward compatible)

TLS 1.2 and 1.3 with PQC key exchange

PQ-ready

Low

Tier 3

Not PQ-ready

No PQC key exchange

Not PQ-ready

High

How to prioritize your migrations

  • Tier 1 represents the strongest security using only TLS 1.3 with PQC key exchange. These resources already meet the target state.
  • Tier 2 represents a backward-compatible PQ-ready configuration. Endpoints support both TLS 1.2 and TLS 1.3, with PQC key exchange negotiated on TLS 1.3 connections. Migration priority is low because these resources already provide quantum-resistant protection for clients that support TLS 1.3, while maintaining TLS 1.2 compatibility for legacy clients. Migrate to Tier 1 when client-side analysis confirms that the connecting clients support TLS 1.3 with PQC key exchange.
  • Tier 3 covers resources that aren’t PQ-ready. This includes endpoints without TLS 1.3 support, endpoints with TLS 1.3 but without PQC key exchange policies. These resources require immediate attention.

Assessment scope

The scanner evaluates the following AWS edge services that terminate TLS connections on behalf of your applications.

  • Edge services:
    • Application Load Balancer (ALB), Network Load Balancer (NLB) listeners with HTTPS, TLS, and TCP SSL protocols are evaluated.
    • API Gateway REST APIs are evaluated for AWS Regional and private endpoints along with API Gateway HTTP APIs (v2) and WebSocket APIs (v2).
  • Excluded edge services:
    • CloudFront distributions are excluded from the PQC readiness scope because TLS 1.3 with hybrid post-quantum key exchange is automatically enabled across existing CloudFront TLS security policies for viewer-to-edge connections. No customer action is required for inbound (viewer-facing) PQC on CloudFront.
  • Recommended approach for Classic load balancer:
    • For Classic Load Balancers, AWS recommends migrating to ALB or NLB. Classic Load Balancers don’t support TLS 1.3 or PQC key exchange and can’t be made PQ-ready.

How the solution works

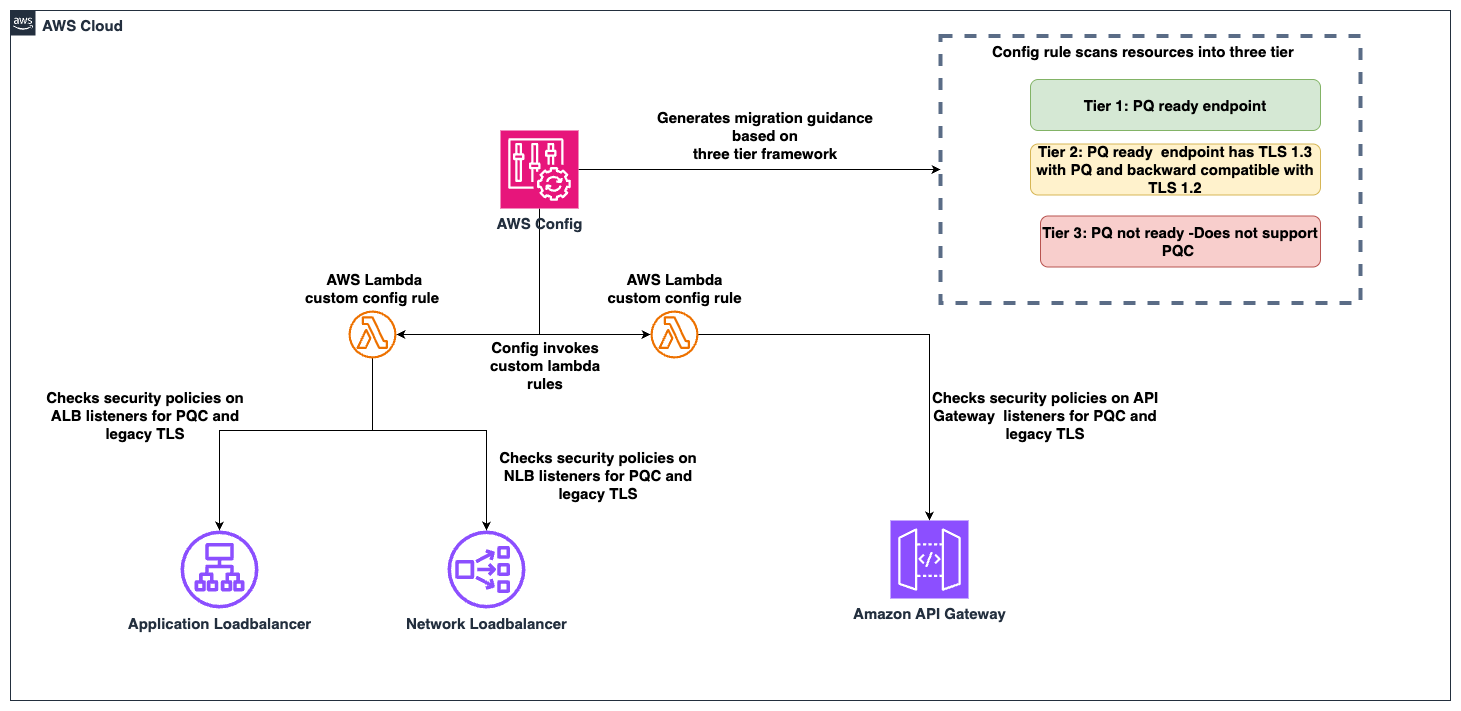
AWS Config enables continuous monitoring and evaluation. Conformance packs enable organization-wide deployment. AWS Lambda is a serverless compute service that runs code to perform security policy evaluation based on the AWS Config rules. AWS Serverless Application Model (AWS SAM) is an open source framework used for deploying the AWS Lambda functions.

Figure 1: PQC readiness solution architecture

Figure 1: PQC readiness solution architecture

The PQC Readiness Scanner conformance pack implements four custom AWS Config rules powered by two Lambda functions:

Rule

What it checks

Non-compliant result

ELB PQ-ready

Load balancer listeners use security policies that support TLS 1.3 with PQC key exchange algorithms

Policy doesn’t include PQC support, the resource is marked with a recommended upgrade policy

ELB legacy TLS

Load balancer listeners allow TLS 1.0 or 1.1 connections

Legacy protocols are configured, the resource is flagged.

API Gateway PQ-ready

API Gateway endpoints use security policies that support TLS 1.3 with PQC key exchange algorithms

Policy doesn’t include PQC support, the resource is marked with a recommended upgrade policy

API Gateway legacy TLS

API Gateway endpoints allow TLS 1.0 or 1.1

Legacy protocols are configured, the resource is flagged.

Prerequisites

Before deploying the solution, you need:

  • AWS Command Line Interface (AWS CLI) configured with appropriate permissions
    aws configure
    aws sts get-caller-identity  # Verify

  • Python 3.12 installed. The Lambda runtime requires this version.
    python3 --version  # Should show 3.12.x

  • AWS SAM CLI installed (Installation Guide)
    pip install aws-sam-cli
    
    # Verify
    sam --version

  • AWS Config enabled in your target AWS Region.
    • Configure it to record (This step is not needed if your accounts are recording all resources by default)
      • AWS::ElasticLoadBalancingV2::LoadBalancer
      • AWS::ApiGateway::RestApi
      • AWS::ApiGatewayV2::Api resource types.
    • Enable via AWS Config Console → Recorder → Recording Strategy → Select specific resource types (Follow the steps in manual setup for AWS Config recording strategy for specific resource types)

Steps to deploy the PQC Readiness Scanner

Deploy the PQC Readiness Config Scanner in three phases. Complete deployment commands and configuration details are available in the GitHub repository. The Lambda functions must be deployed first because the conformance pack references their ARNs as parameters. See the GitHub repository for details.

Deploy to single account:

  1. Clone and Build:
    git clone https://github.com/aws-samples/sample-PQC-Readiness-using-AWS-Config.git
    
    cd sample-PQC-Readiness-using-AWS-Config/installation
    
    sam build

  2. Deploy to One or More Regions:
    # Make script executable (first time only)
    chmod +x deploy-per-regions.sh
    
    # Deploy to a single region
    ./deploy-per-regions.sh us-east-1
    
    # Deploy to multiple regions
    ./deploy-per-regions.sh us-east-1 us-west-2 eu-west-1

    Type y and continue if you have enabled AWS Config recording for these resources or its by default recording all resources.

    Figure 2: Type y and continue if you have enabled AWS Config recording for these resources or its by default recording all resources.

  3. The script automatically:
    • Deploys Lambda functions via SAM
    • Deploys conformance pack (creates Config rules)
    • Verifies deployment success
    • Provides clear status messages

The deployment creates two Lambda functions that perform PQ-ready and legacy TLS checks. It provisions IAM roles with least-privilege permissions for ELB, ALB, NLB, and API Gateway describe operations. Lambda permissions allow AWS Config to invoke the functions.

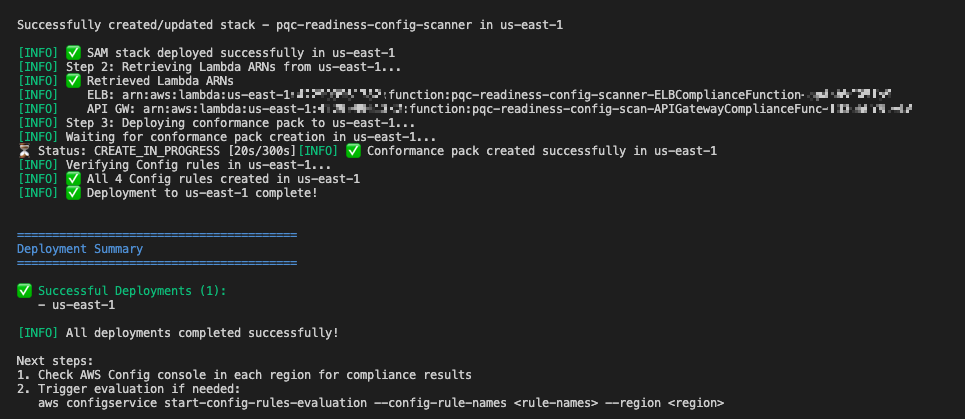
Example screen-print of how a successful deployment looks like.

Figure 3: Example screen-print of what a successful deployment looks like.

Multi-account deployment (Organizations):

For organization-wide deployment across multiple AWS accounts, use CloudFormation StackSets to deploy Lambda functions to each account.

Important Constraint: AWS Config CUSTOM_LAMBDA rules require the Lambda function to exist in the same account as the Config rule. You cannot use a centralized Lambda in one account to evaluate resources in other accounts.

Prerequisite: Shared S3 Bucket

Before packaging, create an S3 bucket accessible by each target account in your organization. This bucket will host the Lambda deployment artifacts that CloudFormation StackSets pulls into each member account.

# Create the shared S3 bucket (run from management/central account)
aws s3 mb s3://<your-org-shared-bucket> --region us-east-1

Grant read access to the target accounts using one of the following options:

aws s3api put-bucket-policy \
  --bucket <your-org-shared-bucket> \
  --policy '{
    "Statement": [
      {
        "Sid": "BucketOwnerFullAccess",
        "Effect": "Allow",
        "Principal": {
          "AWS": "arn:aws:iam::<bucket-owner-account-id>:root"
        },
        "Action": "s3:*",
        "Resource": [
          "arn:aws:s3:::<your-org-shared-bucket>",
          "arn:aws:s3:::<your-org-shared-bucket>/*"
        ]
      },
      {
        "Sid": "CrossAccountReadAccess",
        "Effect": "Allow",
        "Principal": {
          "AWS": [
            "arn:aws:iam::<account-id-1>:root",
            "arn:aws:iam::<account-id-2>:root"
          ]
        },
        "Action": ["s3:GetObject", "s3:ListBucket"],
        "Resource": [
          "arn:aws:s3:::<your-org-shared-bucket>",
          "arn:aws:s3:::<your-org-shared-bucket>/*"
        ]
      }
    ]
  }'

Replace <account IDs> with the AWS account IDs where StackSets will deploy the Lambda functions.

Note: The bucket must be in the same region as the StackSet deployment regions. For multi-region deployments, create one bucket per region and run sam package separately for each.

Step 1: Build and Upload Lambda Packages to S3

Run the packaging script from the installation/ directory:

cd installation

# Make script executable (first time only)
chmod +x deploy-stacksets.sh

# Build, package, upload to S3, and generate resolved template
./deploy-stacksets.sh <your-org-shared-bucket>

This script automatically:

  • Builds Lambda functions using SAM
  • Creates ZIP packages
  • Uploads ZIPs to the shared S3 bucket
  • Generates packaged-template.yaml with S3 values baked in (no parameters needed at deploy time)
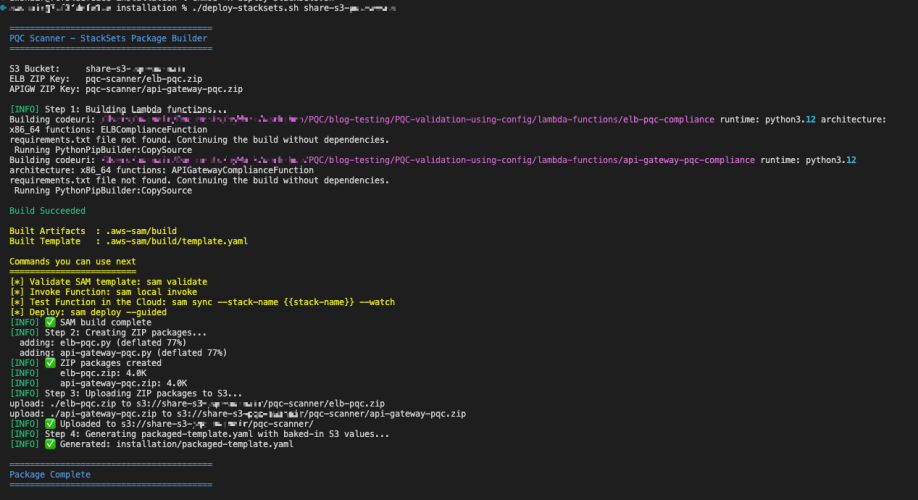
Sample script output of successful upload of the lambda packages to S3 bucket

Figure 4: Sample script output of successful upload of the lambda packages to S3 bucket

Step 2: Deploy Lambda Functions via StackSets

Run the following from the management account (or delegated admin account):

# Create StackSet (--region sets the StackSet "home region" where it is managed)
aws cloudformation create-stack-set \
  --stack-set-name pqc-readiness-lambda-functions \
  --template-body file://packaged-template.yaml \
  --capabilities CAPABILITY_IAM \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=false \
  --region us-east-1

# Deploy stack instances to member accounts
# --regions = target regions where Lambda functions are deployed in member accounts
# --region  = must match the StackSet home region above
aws cloudformation create-stack-instances \
  --stack-set-name pqc-readiness-lambda-functions \
  --deployment-targets OrganizationalUnitIds=ou-xxxx-xxxxxxxx \
  --regions us-east-1 \
  --region us-east-1

Important — StackSet home region vs deployment regions:

  • --region (on each CLI command) = the StackSet home region where the StackSet resource lives. Subsequent operations (describe, update, delete) must specify this same region.
  • --regions (on create-stack-instances) = the deployment target region(s) where stack instances are created in member accounts.
  • These are independent values. Specify --region explicitly to avoid accidental deployment to your CLI’s default region.

Note: SERVICE_MANAGED StackSets must be created from the management or delegated admin account. The management account itself is excluded from stack instance deployments — use deploy-per-regions.sh separately if you need the scanner in the management account.

Step 3: Deploy Organization Conformance Pack

aws configservice put-organization-conformance-pack \
  --organization-conformance-pack-name pqc-legacy-tls-compliance \
  --template-body file://conformance-packs/pqc-legacy-tls-conformance-pack.yaml

This creates Config rules in each member account that reference their local Lambda functions.

    Migration guidance and prioritization

    The three-tier system provides PQC migration priorities:

    High priority – Tier 3 (not PQ-ready):

    • Target: Resources without PQC support. This includes endpoints not using PQ-ready security policies, endpoints that still allow TLS 1.0 or 1.1.
    • Action: Upgrade to a PQ-ready policy containing PQ in its name, such as those ending with -PQ-2025-09 (see Elastic Load Balancing security policies documentation for the full list).
    • Important: Before upgrading to a PQ-ready policy, audit your client TLS versions. PQ-ready policies require TLS 1.3 support; legacy clients that only support TLS 1.2 or earlier will fail to negotiate a connection. Start with a Tier 2 backward-compatible policy (which supports both TLS 1.2 and 1.3 with PQC), monitor connection logs for TLS negotiation failures, and only move to a Tier 1 TLS 1.3-only policy after confirming that your clients support TLS 1.3 with PQC key exchange.
    • Risk: Endpoints don’t support post-quantum cryptography for data in transit. Legacy TLS protocols are vulnerable to current cryptographic attacks.

    Low priority – Tier 2 (PQ-ready, backward compatible):

    • Target: Resources using TLS 1.3 + PQ-ready policies that also support TLS 1.2 for backward compatibility.
    • Action: Consider TLS 1.3-only policies when client compatibility analysis confirms connecting clients support TLS 1.3.
    • Risk: Minimal. These resources already support PQ-TLS with TLS 1.3 connections. TLS 1.2 and earlier fallback maintains backward compatibility, which might indicate some clients aren’t negotiating in PQ-TLS. Remediation is to monitor logs, identify the volume of these connections and clients and plan migration for these clients to use TLS 1.3 with PQ-TLS.

    No action – Tier 1 (PQ-ready, optimal):

    • Target: Resources using TLS 1.3 only with PQC key exchange: These resources meet the target state. No migration needed.

    Viewing the results

    In each member account, navigate to AWS Config Console in the deployed region.

    Conformance Pack View

    Go to AWS Config → Conformance packs and look for:

    OrgConformsPack-pqc-legacy-tls-compliance-

    Note: Organization conformance packs are prefixed with OrgConformsPack- and have a random suffix appended (e.g., OrgConformsPack-pqc-legacy-tls-compliance-gyv22je0).

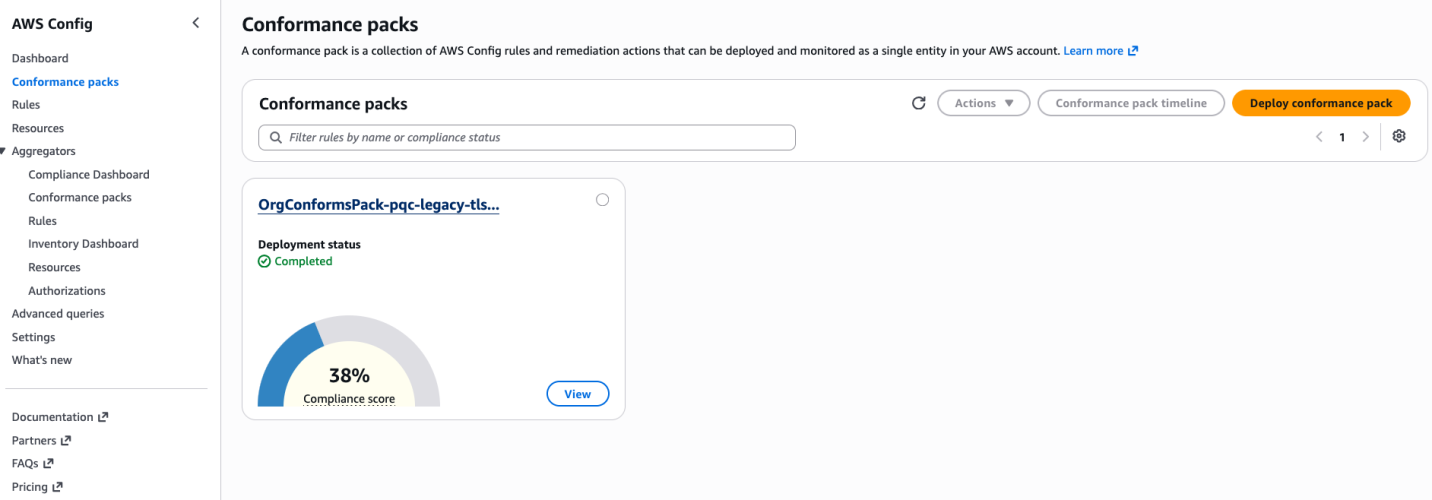
    PQC Conformance Pack Compliance Score is the percentage of the number of compliant rule-resource

    Figure 5: PQC Conformance Pack Compliance Score is the percentage of the number of compliant rule-resource

    Click the conformance pack to see an overall compliance summary across all 4 rules.

    Individual Rules View

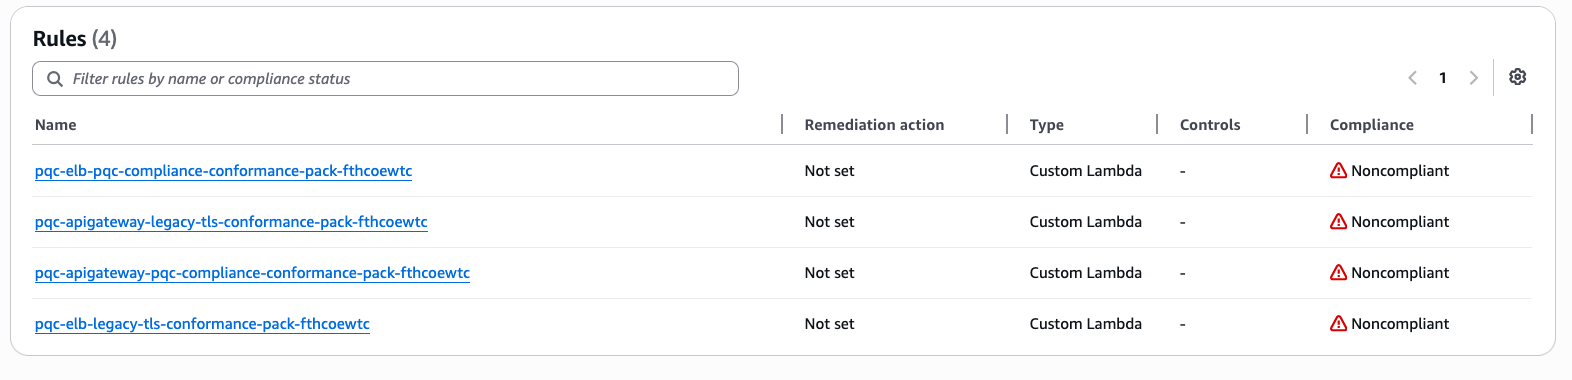
    Go to AWS Config → Rules and find 4 rules with prefix pqc-:

    • pqc-elb-pqc-compliance-conformance-pack-
    • pqc-elb-legacy-tls-conformance-pack-
    • pqc-apigateway-pqc-compliance-conformance-pack-
    • pqc-apigateway-legacy-tls-conformance-pack-

    Click any rule to view:

    • Compliant vs non-compliant resource counts
    • Detailed annotations for each resource
    • Resource ARNs and current security policy configurations
    Visibility into Config rules status inside the conformance pack

    Figure 6: Visibility into Config rules status inside the conformance pack

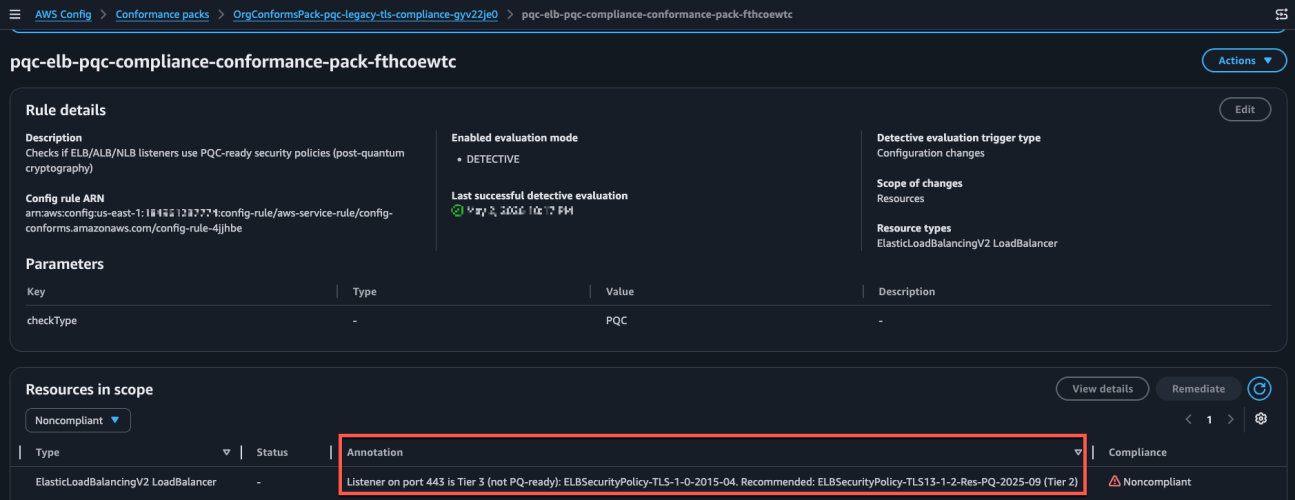
    Sample image of the config rule findings and annotation describing the migeration guidance based on 3-tier classification.

    Figure 7: Sample image of the config rule findings and annotation describing the migration guidance based on 3-tier classification.

    Conclusion

    After deploying the PQC Readiness Scanner, you gain visibility into TLS posture across AWS edge services, which reduces manual configuration reviews. The tier system provides specific upgrade recommendations so teams can understand next steps without cryptographic expertise. The scanner automatically detects configuration changes to help new deployments maintain readiness standards. Built-in AWS Config reporting supports audit requirements and demonstrates measurable progress toward PQC readiness.

    Deploy the PQC Readiness Scanner and review your results with PQC Readiness Scanner. Start migration with high priority Tier 3 resources and monitor progress across your accounts using AWS Config aggregators.

    Additional resources

    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS Config re:Post or contact AWS Support.

    Pravin Nair

    Pravin Nair

    Pravin is a Senior Security Solutions Architect specializing in data protection and privacy at AWS. He partners with customers to architect secure, scalable cloud solutions that address complex security challenges across encryption, infrastructure protection, and privacy engineering. His expertise spans encryption at rest and in transit, infrastructure security, privacy-based architectures, and emerging security domains including generative AI security and post-quantum cryptography.

    Securing client confidentiality at scale: Automated data discovery and governed analytics for legal workloads

    Post Syndicated from Rohan Kamat original https://aws.amazon.com/blogs/big-data/securing-client-confidentiality-at-scale-automated-data-discovery-and-governed-analytics-for-legal-workloads/

    Automating data security and analytics for legal documents presents a unique challenge when your legal team stores documents with strong access controls, organized by client and matter, encrypted at rest, and governed by well-defined policies. But what happens when you want to run analytics across those repositories? The typical path is extracting content into separate data pipelines or third-party tools, which fragments your governance model and introduces new risks. Law firms and corporate legal departments operate under distinct obligations that make data governance non-negotiable. Attorney-client privilege, work product doctrine, and professional conduct rules impose strict duties around how client information is handled, accessed, and disclosed. Governance failure in this context isn’t just a compliance gap, it can result in privilege waiver, disqualification from representation, or disciplinary action.

    Legal professionals use ethical walls, also called information barriers, as structural safeguards that prevent the flow of confidential information between teams within a firm that represent adverse or potentially conflicting interests. Professional conduct rules mandate these barriers, and failure to maintain them can result in firm disqualification, malpractice liability, or regulatory sanctions.

    Privilege boundaries are equally critical. Attorney-client privilege and work product protection apply only when you properly control access to the underlying material. If you expose privileged documents or metadata about their contents to unauthorized individuals, you risk losing your privilege protection. When organizations fail to maintain reasonable controls over privileged material, courts might find that they have waived their privilege. You should therefore actively manage your access governance, not only as a security concern but as a legal preservation requirement.When you extract content into separate analytics systems or grant broader access than your matter structures support, you create pressure on both protections. You gain visibility but lose confidence in your controls.

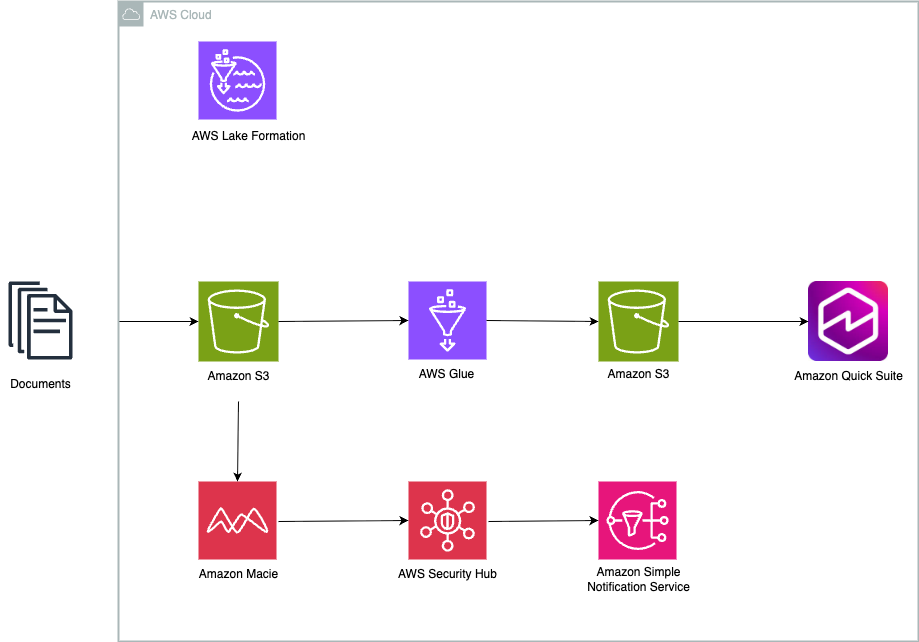
    In this post, we show you a reference architecture that automates sensitive data discovery across legal document repositories on Amazon Web Services (AWS), demonstrate how to capture structured findings as a compliance dataset, and guide you through building a governed analytics workspace that maintains your security boundaries. You walk away with a practical model for building security and analytics into the same lifecycle, without moving documents outside their system of record.

    Analytics shouldn’t weaken governance

    Most legal organizations have invested heavily in securing their document repositories. You store documents in structured storage, organized by client and matter. You access controls map to matter boundaries (the organizational and access structures that separate one client engagement from another). You establish retention and hold policies.The difficulty starts when teams want to analyze what’s inside those repositories. Running analytics typically means copying content into a separate system, standing up a new data pipeline, or granting broader access than existing matter structures support. Each of these steps introduces governance gaps. Manual reporting fills some of the void, but it doesn’t scale and can’t provide continuous visibility. What’s missing is a model where security controls and analytics reinforce each other, where the act of discovering sensitive data also produces the dataset that you use for reporting, and where governance applies once and carries through every downstream operation.

    Automation addresses this by combining continuous sensitive data discovery with governed analytics, built on discovery metadata rather than document copies. This automated approach delivers four key advantages:

    • No document movement. Your files stay in their system of record. Analytics runs against structured discovery metadata, not document content, so governance boundaries remain intact.
    • Continuous discovery instead of manual scanning. Automated classification identifies regulated and sensitive information on an ongoing basis, replacing periodic manual reviews with on demand visibility.
    • Unified governance. You define matter-aligned access policies once, and they carry through from document storage to findings analytics and compliance reporting.
    • Built-in audit readiness. A durable record of discovery findings and remediation actions accumulates automatically over time, giving you structured evidence for client reviews and regulatory inquiries.

    Reference Architecture

    The following architecture shows how continuous discovery, governance, and compliance operations can work together without copying legal documents into analytics systems.

    This reference architecture illustrates how law firms and corporate legal departments can automate sensitive data discovery and compliance analytics on AWS without moving documents outside their system of record

    Architecture walkthrough

    Store and protect documents in Amazon Simple Storage Service (Amazon S3)

    Store your legal documents in Amazon S3, which serves as the system of record for document content. Align your buckets and prefixes to client and matter structures so that access controls map directly to matter boundaries. Where your retention or legal hold requirements demand it, apply S3 Object Lock to enforce immutability. You can encrypt your data using AWS Key Management Service (AWS KMS), which gives you centralized control over encryption keys and policies.

    Discover and classify sensitive data with Amazon Macie

    You will configure Amazon Macie to continuously analyze your document repositories. Macie identifies regulated information such as personally identifiable information (PII), financial data, and other sensitive content and produces structured findings that describe what Macie identified and where it exists. This provides ongoing visibility into data exposure without requiring document movement or manual scanning.

    Catalog and govern findings with AWS Glue and AWS Lake Formation

    You will use AWS Glue to catalog the findings dataset and maintain its schema so it stays query-ready. Apply AWS Lake Formation tag-based policies to govern access, aligning tags to client, matter, and confidentiality tier. This approach enforces ethical walls and least-privilege access consistently across analytics and reporting activities.

    AI-powered chat agent using Amazon Quick Suite

    You can create custom chat agents to tailor conversational interfaces for specific legal business needs. These agents can be configured with legal-specific knowledge bases, connected to relevant document repositories, and customized with instructions appropriate for legal workflows. You can use this chat agent to interact with your legal documents through natural language conversation for capabilities like:

    • E-Discovery:Search and analyze large volumes of legal documents to quickly find relevant information across your document repository.
    • Contract Analysis:Review contracts and automatically extract key terms, clauses, and obligations to streamline your contract review process.

    The chat agent can help you navigate complex document sets through conversational queries, making legal research and document review more efficient and accessible.

    Analyze and report with Amazon Quick Sight

    You will use Amazon Quick as your compliance operations workspace. Quick provides a unified environment where your teams can query findings, generate dashboards, track remediation actions, and produce audit-ready reports. The agentic AI capabilities of Amazon Quick can autonomously build analyses, surface anomalies across matters, generate executive summaries for client reviews, and proactively recommend remediation priorities based on finding severity and trends. Combined with built-in data stories for automated narrative generation and pixel-perfect paginated reports for regulatory submissions, Quick reduces the time from discovery to action while keeping your teams within a governed interface aligned to matter-based permissions. Rather than switching between separate visualization, workflow, and reporting tools, your legal and compliance teams can review findings, manage response activities, and collaborate all within a single workspace that respects ethical walls and privilege boundaries.

    Escalate high-severity findings

    For high-severity findings that demand immediate attention, route alerts through AWS Security Hub or Amazon Simple Notification Service (Amazon SNS) to trigger escalation workflows. This connects visibility directly to action when your teams identify sensitive data risks.

    Why this approach works for legal

    Documents stay where they belong. Your files remain in Amazon S3, aligned to client and matter boundaries. No content moves into separate analytics pipelines.Ethical walls remain intact. Because analytics is built on discovery findings and not document copies, you can govern access to findings using the same matter-aligned controls that apply to documents. Compliance and security teams gain visibility without expanding document access.Discovery runs continuously, not periodically. Rather than scheduling quarterly or annual scans, you maintain a current view of sensitive data across your repositories.

    Governance applies once and carries through. Lake Formation tag-based policies govern findings access at the catalog level. You define your matter and confidentiality mappings once, and they carry through to every dashboard, query, and report.Audit readiness is built in. Instead of assembling reports manually before a client review or regulatory inquiry, you maintain a historical record of discovery findings and remediation actions. You can demonstrate your posture over time with consistent, structured evidence.

    Security and analytics reinforce each other. Your analytics capability is built on top of your security controls, not alongside them. Strengthening one strengthens the other.

    Cost considerations

    The primary cost drivers for this architecture include:

    • Amazon Macie: You pay based on the number of S3 buckets evaluated and the volume of data inspected for sensitive data discovery. Review Amazon Macie pricing for current rates.
    • Amazon S3: Storage costs for both your document repositories and the compliance intelligence bucket. Consider S3 lifecycle policies to tier older findings into lower-cost storage classes.
    • AWS Glue and AWS Lake Formation: Charges for crawlers and catalog storage. For most implementations, these costs are modest.
    • Amazon QuickSight: Per-user pricing based on the edition that you select (Standard or Enterprise). Enterprise edition supports row-level and column-level security, which aligns well with matter-based governance.
    • Amazon EventBridge, AWS Security Hub, and Amazon SNS: Charges based on event volume and notifications delivered. For findings-based workflows, these costs are generally low.

    Use the AWS Pricing Calculator to estimate costs based on your repository size, user count, and discovery frequency.

    Getting started

    Start by identifying a representative set of document repositories in Amazon S3. We recommend that you start with two or three matters that span different practice areas and confidentiality tiers.

    1. Turn on Amazon Macie for those repositories and configure automated sensitive data discovery.
    2. Catalog the findings dataset with AWS Glue and apply Lake Formation tag-based access policies aligned to your matter structure.
    3. Build your first Amazon Quick Sight dashboard to visualize findings by matter, sensitivity type, and severity.
    4. Define escalation rules in AWS Security Hub or Amazon SNS for high-severity findings.

    After you validate this workflow against your initial repositories, expand gradually. Add more repositories to Macie discovery. Refine your governance tags to reflect practice areas and confidentiality tiers. Extend your dashboards from basic posture visibility to trend analysis and remediation tracking.The goal isn’t to build a comprehensive analytics solution all at once. Start with a secure foundation where discovery findings, governance, and reporting operate together in a way that aligns with your legal workflows, and then expand from there.

    Conclusion

    You don’t have to choose between protecting client data and understanding it. By building analytics on top of governed discovery findings and using a unified compliance workspace, you gain visibility into your data posture without weakening confidentiality boundaries.This approach brings security, governance, and analytics together in a way that reflects how legal work is actually structured. It provides continuous visibility, supports audit readiness, and delivers insight without requiring documents to move outside their system of record.

    Next steps

    Review the Amazon Macie User Guide to understand sensitive data discovery configuration options and Amazon Quick Sight documentation to evaluate dashboard and row-level security capabilities.

    Contact your AWS account team to discuss implementation support for legal and compliance workloads.


    About the authors

    Photo of Author - Rohan Kamat

    Rohan Kamat

    Rohan Kamat is a Solutions Architecture Leader within HCLS with extensive experience in cloud architecture, cybersecurity, Identity and Access Management, and enterprise networking. Rohan focuses on helping architects build both depth in cloud technologies and strength in executive communication, making sure they can confidently guide organizations through business and technical transformation. Outside of his professional work, Rohan enjoys time with his family, organizing community cricket events, and exploring fitness and wellness activities like pickleball and ping pong. He also enjoys planning travel experiences that bring people together and create lasting shared memories.

    Photo of Author- Miguel Lopez Luis

    Miguel Lopez Luis

    Miguel Lopez Luis is an AWS Solutions Architect who works with small and medium businesses across the United States. He graduated with a Bachelor’s degree in Cybersecurity from Bellevue University in Nebraska and is a member of the Omega Nu Lambda Honor Society. Leveraging his extensive expertise in business management, Miguel is passionate about planning strategic initiatives, leading cross-functional teams, and mentoring others. In his personal time, he enjoys activities that involve travel, sports, and cooking.

    Photo of Author - Pranali Khose

    Pranali Khose

    Pranali Khose is an AWS Solutions Architect based in Seattle. She works directly with small and medium business (SMB) customers across the United States, to design and implement cloud solutions that address their unique business challenges and accelerate digital transformation. Pranali holds a Master of Science in Computer Science from the University of Texas at Arlington.

    Streaming CloudWatch metrics to VPC-based OpenTelemetry collectors using Lambda

    Post Syndicated from Behzad Dastur original https://aws.amazon.com/blogs/architecture/streaming-cloudwatch-metrics-to-vpc-based-opentelemetry-collectors-using-lambda/

    Organizations are increasingly drawn to open-source observability frameworks like OpenTelemetry. They seek to reduce costs associated with third-party licensing and avoid vendor lock-in. Combining OpenTelemetry collectors with Amazon CloudWatch Metric Streams helps enterprises pursue their observability goals while eliminating third-party licensing fees and achieving sub-minute latency for real-time alerting. CloudWatch Metric Streams offer built-in support for publishing to OpenTelemetry endpoints, but organizations that self-host OpenTelemetry collectors within their VPC need a way to bridge the gap between metric streams and internal HTTP endpoints.

    In this post, we demonstrate an approach we used to address this challenge for a customer by implementing an AWS Lambda transformation function that streams Amazon CloudWatch metrics directly to internal OpenTelemetry collectors running within a VPC.

    Common observability challenges overcome with OpenTelemetry

    Traditional monitoring becomes expensive and difficult to manage as cloud infrastructure grows. Many enterprises face a choice between expensive third-party observability solutions and the technical limitations of legacy metric collection methods. When organizations adopt cloud-native solutions and transition from monolithic applications to microservices, metric collection for observability becomes even more important.

    Many operations and development teams face the challenge of building monitoring solutions that include tools and frameworks from different vendors and open-source projects, with different specifications and protocols, resulting in complex and fragmented landscape that’s difficult to maintain. OpenTelemetry is becoming the primary way to implement observability for many organizations. OpenTelemetry is an open-source framework for collecting traces, metrics, and logs. It works with any observability platform. Amazon CloudWatch, the AWS monitoring service, provides an open source distribution of OpenTelemetry called AWS Distro for OpenTelemetry to help you get started with OpenTelemetry. OpenTelemetry gained industry adoption primarily because of the standardization it provides enterprises through the following benefits:

    • Single set of APIs and libraries to capture distributed traces and metrics that can be sent to any observability platform
    • Future-proofing by avoiding vendor lock-in and enabling flexibility in choosing observability backends
    • Broad vendor support because it is open sourced and natively supported by numerous vendors

    Pull vs push-based monitoring architecture

    In a pull model like Prometheus, the monitoring server periodically scrapes metrics from endpoints. Although this model provides more control over query frequency, it runs into challenges at scale. Our customer’s current monitoring solution with Prometheus and Amazon CloudWatch exporter using a pull-based approach resulted in higher API throttling. This caused metric loss and created gaps in observability data for business-critical systems. The frequent polling approach in this model also resulted in higher costs from API calls. This polling solution did not satisfy their requirement of sub-minute latency for real-time alerting.

    To overcome these challenges, we recommend a push–based architecture. The push-based solution, using CloudWatch Metric Streams to push metrics to OpenTelemetry collector, addresses these challenges by reducing frequent polling and API calls, enabling near real-time data transmission, and potentially eliminating licensing costs from using third-party solutions. Using OpenTelemetry’s push-based model, enterprise applications can send telemetry (traces, metrics, logs) to a collector or backend that offers significant benefits for real-time observability, such as:

    • Event-driven architecture: The push approach transmits data in near real-time by triggering collection based on events, not periodic polling. This is particularly valuable when using OpenTelemetry collectors that can push metrics to multiple services like Amazon Managed Prometheus (AMP), AWS X-Ray, Amazon CloudWatch, and Amazon OpenSearch.
    • Cost efficiency: Push models are significantly more cost-effective than pull models. Instead of continuously scanning large datasets, systems only process and transmit data when relevant events occur, reducing both computational overhead and data transfer costs.
    • Scalability: The OpenTelemetry collector serves as a central hub that can scale horizontally to handle varying traffic volumes while providing at-least-once delivery guarantees with automatic retry mechanisms.
    • No licensing costs: The Apache 2.0 license is free and royalty-free, meaning you can use, modify, and distribute OpenTelemetry without any licensing fees or ongoing costs.
    • No vendor lock-in: The permissive nature of Apache 2.0 means you’re not tied to any specific vendor’s implementation or support model. You can modify the code, switch between different OpenTelemetry distributions (like AWS Distro for OpenTelemetry), or even fork the project if needed.

    How we built a scalable push-based observability solution

    Our solution involves configuring an Amazon Data Firehose stream, that receives Amazon CloudWatch metrics and sends them to an OpenTelemetry collector within our customer’s VPC. Because of their strict data privacy requirements, our customer required the metric data and the OpenTelemetry collector to be within their VPC. A Network Load Balancer (NLB) serves as the internal endpoint to receive metric streams. Amazon Data Firehose natively supports data delivery to HTTP endpoints, but these endpoints must be public – they cannot be private endpoints inside a VPC. To overcome this limitation, we use the Amazon Data Firehose transform configuration, that invokes a Lambda function synchronously, which then securely pushes the metrics through the NLB endpoint to the collector running within the VPC. With this solution our customer could then aggregate and display all their metrics from AWS, other accounts, and on-prem systems in a single pane of glass dashboard.

    The following diagram shows the architectural blocks of the solution:

    Figure 1: Reference architecture for the Amazon CloudWatch Streams to OpenTelemetry collector solution

    The solution consists of 4 main components – CloudWatch Metric Streams, Amazon Data Firehose, AWS Lambda, and the OpenTelemetry collector.

    1. CloudWatch metric streams: CloudWatch Metric streams enables you to stream CloudWatch metrics in near real-time, with minimal setup and without writing code. In this architecture, CloudWatch streams metrics to our configured Amazon Data Firehose stream. With CloudWatch Metric Streams, you can stream metrics in OpenTelemetry 0.7, 1.0, and JSON formats. This architecture uses JSON format as the stream output.
    2. Amazon Data Firehose stream: A fully managed service that reliably captures, transforms, and delivers real-time streaming data to the customer’s internal endpoint.
    3. Lambda transform function: Amazon Data Firehose supports Lambda-based data transformation that allows you to preprocess, enrich, filter, or modify streaming data before delivery to destinations. Because Firehose cannot deliver metrics directly to private VPC endpoints, we use Firehose’s data transformation feature with Lambda to bridge this gap and deliver metrics to internal endpoints. Amazon Data Firehose buffers incoming data before synchronously invoking the Lambda function that streams the metrics to the internal HTTP endpoint.
    4. The OpenTelemetry collector: In this solution, the OpenTelemetry collector runs as a container in an EC2 instance. The collector is a central hub that receives, processes, and forwards telemetry data (metrics, traces, and logs) from various sources to multiple destinations in a vendor-neutral way. The OpenTelemetry collector operates through three primary components that work together in a processing flow: Receivers accept data in specified formats (like Prometheus or OpenTelemetry Protocol (OTLP)) and translate it into OpenTelemetry’s internal format; Processors manipulate and enrich the data as it flows through (filtering unnecessary data, batching for performance, transforming to mask sensitive information, or adding metadata like Kubernetes attributes); and Exporters send the processed data to destination backends such as Grafana Cloud, AWS X-Ray, Lightstep or Honeycomb.

    The reference architecture also shows the following components:

    1. Amazon Simple Storage Service (Amazon S3) bucket: The S3 bucket is a redundant destination for the CloudWatch Streams. Because our Lambda transform function sends the data directly to OpenTelemetry endpoint, no metrics are sent to the S3 destination, and it does not incur any cost.
    2. Network Load Balancer: This NLB operates at the transport layer of the Open Systems Interconnection (OSI) model. In this architecture, the NLB distributes TCP traffic to the OpenTelemetry collectors running on EC2 Instances in the internal subnet within the VPC.
    3. Amazon Elastic Compute Cloud (Amazon EC2) instance: In this architecture, we run the OpenTelemetry collector on the EC2 instances. The instances run in the private subnet within our VPC.

    The following sections detail the steps for deploying this solution in your own AWS environment. You can deploy this solution using either AWS CloudFormation or the AWS Command Line Interface (AWS CLI). Deployment time and complexity will vary based on your familiarity with these AWS services.

    Implementation details

    Prerequisites:

    Before deploying this solution, verify that you have the following:

    • An AWS account with permissions to create CloudWatch Metric Streams, Amazon Data Firehose, Lambda, and EC2 resources
    • AWS CLI v2 installed and configured.
    • AWS Serverless Application Model (AWS SAM) CLI installed.
    • A VPC with at least two subnets configured in different Availability Zones and security groups to allow necessary inbound and outbound traffic.

    We can implement this architecture in two ways: deploying with AWS CloudFormation or deploying with the AWS CLI.

    Option 1: Deploying with AWS CloudFormation

    This walkthrough creates a CloudFormation stack, that deploys an Amazon Data Firehose stream, Amazon CloudWatch stream, S3 bucket, Lambda function for data transformation.

    Access the CloudFormation template by cloning the git repository.

    Step 1 – Package the Lambda artifacts for the CloudFormation template.

    This step creates the cf-packaged-file.yaml file and publishes the Lambda Layer code packaged to the specified S3 bucket cf-stage-bucket-203918862653:

    ~> pwd
       sample-cloudwatch-metrics-stream-otel-transformer/cloudformation 
    ~> ./setup_layer.sh 
    ~>
    ~> aws cloudformation package \
        —template-file ./cloudformation-template.yaml \
        —s3-bucket cf-stage-bucket-xxxxx \
        —output-template-file cf-packaged-file.yaml
    
       Uploading to 9813804ccc99d538f6d4ef06c4857bab 223 / 223.0 (100.00%)
       Successfully packaged artifacts and wrote output template to file cf-packaged-file.yaml.
       Execute the following command to deploy the packaged template
      aws cloudformation deploy —template-file ~/code/sample-cwmetrics-   sep25/sample-cloudwatch-metrics-stream-otel-transformer/cloudformation/cf-packaged-file.yaml —stack-name <YOUR STACK NAME>
    

    Step 2 – Create CloudFormation stack using the console.

    1. Sign in as an administrator to the AWS Management Console and use the navigation bar to select your preferred AWS Region for deployment.
    2. Navigate to the CloudFormation dashboard to create stack.
    3. Choose ‘Create Stack’ and choose “Choose an existing template”. Upload the template file and choose the cf-packaged-file.yaml created in the first step.

    1. Configure the key parameters.

    1. Acknowledge the Capabilities to allow CloudFormation to create the necessary LambdaExecutionRole IAM role with the required permissions.

    1. Finally, review and choose ‘Next’ to create the CloudFormation stack.

    Option 2: Deploying with AWS Command Line Interface

    Alternatively, you can run the following steps from a terminal using the AWS CLI to package and create your CloudFormation stack.

    Access the CloudFormation template by cloning the git repository.

    Step 1 – Package the Lambda artifacts for the CloudFormation template.

    This step creates the cf-packaged-file.yaml file and publishes the Lambda Layer code packaged to the specified S3 bucket cf-stage-bucket-203918862653.

    ~> pwd
       sample-cloudwatch-metrics-stream-otel-transformer/cloudformation 
    ~> ./setup_layer.sh 
    ~>
    ~> aws cloudformation package \
        —template-file ./cloudformation-template.yaml \
        —s3-bucket cf-stage-bucket-xxxxxxxxxx \
        —output-template-file cf-packaged-file.yaml
    
       Uploading to 9813804ccc99d538f6d4ef06c4857bab 223 / 223.0 (100.00%)
       Successfully packaged artifacts and wrote output template to file cf-packaged-file.yaml.
       Execute the following command to deploy the packaged template
      aws cloudformation deploy —template-file ~/code/sample-cwmetrics-   sep25/sample-cloudwatch-metrics-stream-otel-transformer/cloudformation/cf-packaged-file.yaml —stack-name <YOUR STACK NAME>

    Step 2 – Create stack using AWS Command Line Interface.

    Create a parameters.json file as follows:

    %~> cat parameters.json 
    [
      {
        "ParameterKey": "Subnet1",
        "ParameterValue": "subnet-xxxxxxxxxx"
      },
      {
        "ParameterKey": "Subnet2",
        "ParameterValue": "subnet-yyyyyyyyyy"
      },
      {
        "ParameterKey": "SecurityGroup",
        "ParameterValue": "sg-xxxxxxxxxx"
      },
      {
        "ParameterKey": "OtelCollectorEndpoint",
        "ParameterValue": "http://your-otel-endpoint:4318/v1/metrics"
      },
      {
        "ParameterKey": "MetricStreamNamespaces",
        "ParameterValue": ""
      },
      {
        "ParameterKey": "S3BucketPrefix",
        "ParameterValue": "cloudwatch-metrics-stream"
      }
    ]

    Run the CloudFormation create-stack CLI as follows:

    ~> aws cloudformation create-stack \
         --stack-name cw-metrics-demo \
         --template-body "file://cf-packaged-file.yaml" \
         --parameters file://parameters.json \
         --capabilities CAPABILITY_NAMED_IAM \
         --region us-east-1 --profile dev

    After you deploy the infrastructure stack, CloudWatch Metric Streams initiates the flow by streaming near real-time metrics from customer applications. Amazon Data Firehose asynchronously invokes the Lambda transform function that sends metrics directly to the OpenTelemetry collector endpoint. You must then configure these collectors to apply additional processing, such as filtering, batching, and enrichment. The collectors forward metrics to one or more observability backends, such as Honeycomb, Jaeger, Grafana Cloud, or other dashboards.

    Clean up

    To avoid incurring unnecessary charges after testing the proof of concept (POC), clean up the resources. You can do so by deleting the CloudFormation stack to remove all deployed resources.

    Option 1: Using the console:

    • Sign in as an administrator to the AWS Management Console and use the navigation bar to select your preferred AWS Region for deployment.
    • Navigate to the CloudFormation dashboard to create stack.
    • Select the ‘cw-metrics-demo’ stack and choose “Delete”.

    Option 2: Using AWS CLI:

    aws cloudformation delete-stack \ --stack-name cw-metrics-demo \ --region us-east-1 --profile dev

    Conclusion

    In this post, we showed how moving from third-party observability tools to CloudWatch Metric Streams with OpenTelemetry can reduce costs and improve performance. The solution we implemented combines AWS streaming with the OpenTelemetry standard to create a flexible and scalable monitoring solution that can adapt to changing requirements while maintaining operational excellence. If you face similar challenges with your observability solution, this approach offers a proven path to reduce costs, improve performance, and maintain control over your monitoring data.


    About the authors

    Streamlined monitoring and debugging for Amazon EMR on EC2

    Post Syndicated from Parul Saxena original https://aws.amazon.com/blogs/big-data/streamlined-monitoring-and-debugging-for-amazon-emr-on-ec2/

    As organizations scale their data processing and analytics workloads on Amazon EMR on EC2, observability across cluster health, job execution, and resource usage becomes increasingly important. Teams often manage log collection across distributed nodes, correlate Amazon EMR steps with underlying YARN applications, and configure monitoring agents to capture the right level of detail for their environment.

    With Amazon EMR release 7.11.0 and updates to the Amazon EMR console, Amazon EMR on EC2 introduces observability capabilities that streamline these workflows further. In this post, we walk you through five key enhancements: Amazon CloudWatch Logs integration, step-level Amazon Simple Storage Service (Amazon S3) logging controls, expanded console UIs for YARN and Tez, Amazon EMR step to YARN application ID mapping, and enhanced custom metrics with updated documentation.

    What’s new

    The following sections cover key improvements across the Amazon EMR console, logging, metrics collection, and documentation to give you deeper, end-to-end visibility into your Amazon EMR clusters and workloads.

    1. CloudWatch Logs integration

    Starting with Amazon EMR release 7.11.0, you can stream cluster logs to Amazon CloudWatch Logs in near real time without requiring custom bootstrap actions or manual agent configuration. With Amazon CloudWatch logging enabled, Amazon EMR automatically captures and streams Amazon EMR step execution logs, Spark driver, and Spark executor logs as they’re generated. This makes them immediately available for monitoring, troubleshooting, and post-mortem analysis through the CloudWatch console or API.

    You can enable CloudWatch logging through the Amazon EMR console during cluster creation or programmatically using the AWS Command Line Interfaced (AWS CLI) and SDK by including the Amazon CloudWatch Agent in your application configuration and specifying your logging preferences in the configuration section.

    With minimal configuration, Amazon EMR captures step logs and Spark driver logs by default, streaming them to a log group named /aws/emr/{cluster_id}. For production workloads requiring stricter organizational and security controls, you can customize the log group name, define a log stream prefix for streamlined filtering, enable encryption with an AWS Key Management Service (AWS KMS) key, and explicitly select which log types to capture. The following example demonstrates a fully customized configuration:

    aws emr create-cluster
    --name "EMR cluster with custom CloudWatch Logs"
    --release-label emr-7.11.0
    --applications Name=Spark Name=AmazonCloudWatchAgent
    --instance-type m7g.2xlarge
    --instance-count 3
    --use-default-roles
    --monitoring-configuration '
    "CloudWatchLogConfiguration":
    "Enabled": true,
    "LogGroupName": "/my-company/emr/production",
    "LogStreamNamePrefix": "cluster-prod",
    "EncryptionKeyArn": "arn:aws:kms:us-east-1:123456789012:key/12345678-1234-1234-1234-123456789012",
    "LogTypes": {
    "STEP_LOGS": ["STDOUT", "STDERR"],
    "SPARK_DRIVER": ["STDOUT", "STDERR"],
    "SPARK_EXECUTOR": ["STDERR", "STDOUT"]
    }
    }
    }'

    This configuration directs the logs to a custom log group (/my-company/emr/production), prefixes log stream names with cluster-prod for consistent identification across clusters, encrypts log data at rest using the specified KMS key, and captures the full set of available log types: step stdout/stderr, Spark driver, and Spark executor output. Because logs are streamed to CloudWatch as they’re written, you have near real-time visibility into job execution without waiting for log aggregation to S3 or establishing direct connectivity to cluster nodes. Combined with CloudWatch Logs Insights, you can run structured querying across log streams, making it straightforward to trace failures, correlate errors across driver and executor logs, and build metric filters or alarms based on specific log patterns.

    2. Step-level S3 logging improvements

    S3 logging capabilities now provide granular control over how step logs are organized and secured. You can now specify a dedicated S3 log destination and AWS KMS encryption key at the individual Amazon EMR step level. This allows different steps within the same cluster to write logs to separate S3 paths with independent encryption configurations. This is particularly useful for multi-tenant clusters or workflows with varying data classification requirements.

    Step-level logging is configured through the StepMonitoringConfiguration parameter, which accepts an S3MonitoringConfiguration object where you can define the target S3 path and an AWS KMS key for encryption at rest:

    "StepMonitoringConfiguration": { "S3MonitoringConfiguration": { "LogUri": "s3://your-s3-bucket/", "EncryptionKeyArn": "arn:aws:kms:your-kms-key-arn" } }

    This configuration is optional. When omitted, the step inherits the default S3 log path and encryption settings defined at the cluster level during creation. With this configuration, you can override logging behavior only for the steps that require it, while maintaining a consistent default for the rest of your workflow.

    3. Enhanced console with direct access to monitoring UIs

    Additional live application UIs are accessible directly from the Amazon EMR Console. These console-hosted interfaces remove the need to configure SSH (Secure Shell) tunnels, set up proxies, or establish any direct network connectivity to cluster nodes to reach application web UIs. The newly added interfaces include:

    • YARN ResourceManager UI – Monitor cluster-wide resource allocation, queue usage, and application lifecycle states across running and completed YARN applications. This interface also provides direct access to container-level logs for running YARN applications, enabling real-time debugging without requiring node-level access.
    • Tez UI – Inspect Hive query execution plans, DAG visualizations, vertex-level performance metrics, and task-level counters for queries executed through the Tez execution engine (for example, Hive and Pig workloads).

    These join the existing Spark History Server and YARN timeline interfaces already available through the console. By surfacing these UIs, administrators can grant developers and analysts visibility into cluster workloads and application diagnostics without exposing direct network access to cluster infrastructure while maintaining tighter security boundaries and preserving full observability into job execution and resource consumption.

    With these additions, Amazon EMR now offers three complementary approaches to accessing application web interfaces, each suited to different operational requirements. Live Application UIs provide console-hosted access to web interfaces on running clusters. They’re recommended for environments where direct network connectivity to cluster nodes must be restricted from end users. On-Cluster Web UIs offer full, unrestricted access to the complete set of native application web interfaces running on cluster nodes, suited for administrators and engineers who require deep, low-level visibility. Persistent Web UIs retain application-level data beyond cluster lifetime, so you can analyze and troubleshoot workloads on terminated clusters. Together, these options give you the flexibility to balance security boundaries, access scope, and data retention based on your team’s specific monitoring and debugging workflows.

    4. EMR step to YARN application ID mapping

    The Amazon EMR console now surfaces the YARN Application ID directly within the EMR step details panel. For each step executing a Spark, Hive, or other YARN-based workload, the console displays the submitted YARN Application ID associated with that step, establishing a direct link between the EMR step abstraction and the underlying YARN application. With this mapping, you can:

    • Directly correlate EMR steps to YARN applications – when a step fails or exhibits unexpected behavior, you can immediately identify the exact YARN application to investigate rather than manually cross-referencing timestamps or job names across interfaces.
    • Access live monitoring tools – with the YARN application ID readily available, you can navigate directly to the YARN ResourceManager Live UI or the Spark History Server to inspect resource consumption, task-level execution details, and application state for both running and completed jobs.
    • Retrieve logs for detailed troubleshooting – the application ID serves as the key lookup for retrieving container-level logs persisted to Amazon S3, significantly reducing the time to root-cause failures or diagnose performance regressions.

    To use this feature, open the Steps tab on your Amazon EMR cluster detail page and select the step that you want to investigate. The YARN Application ID appears in the step details panel. From there, you can use the ID to navigate to the YARN ResourceManager Live UI at http://resourcemanager-host:8088/cluster/app/<application_id>, open the corresponding view in the Spark History Server, or locate the associated container logs in your configured S3 log destination.

    5. Enhanced custom metrics and observability documentation

    By default, Amazon EMR automatically sends cluster-level metrics to Amazon CloudWatch at five-minute intervals, covering YARN application states, node health, HDFS utilization, and I/O activity. With Amazon EMR Release 7.0 and later, enabling the Amazon CloudWatch Agent extends this baseline with additional detailed metrics collected at one-minute intervals across cluster nodes. Furthermore, Amazon EMR 7.1 introduced custom metric classifications that you can use to define precisely which component-level metrics to collect from Hadoop, YARN, and HBase subsystems, like DataNode I/O activity, NodeManager JVM heap utilization, container resource consumption, and HBase performance counters. Each classification supports configurable export intervals, giving you control over collection granularity based on your monitoring requirements.

    After enabled, custom metrics are accessible directly from the Monitoring tab in the Amazon EMR console, where you can use a classification filter to switch between HDFS, YARN, HBase custom metric groupings that you’ve defined. Metric configurations can also be updated on running clusters through the console’s reconfiguration workflow, so you can adapt your monitoring strategy as workload requirements evolve without cluster downtime. For environments using Prometheus, metrics can also be forwarded to Amazon Managed Service for Prometheus and visualized through Grafana dashboards.

    The following documentation and tutorials are available to help you get the most out of these capabilities:

    Getting started

    These observability improvements are available now for Amazon EMR on EC2. To get started:

    1. CloudWatch Logs integration and step-level log configuration: To use these capabilities, launch a new cluster with Amazon EMR release 7.11.0 or later.
    2. For console enhancements: Navigate to your existing Amazon EMR clusters in the AWS Console to access Live Application UI links and YARN Application ID mappings in step details, with no additional configuration required.
    3. For custom metrics: Review our Enhanced Custom Metrics documentation to configure the CloudWatch Agent for publishing Hadoop, YARN, and HBase component metrics using custom classification files.

    Conclusion

    With these enhancements, Amazon EMR on EC2 provides deeper visibility into cluster health, job execution, and resource usage, helping you reduce time to root cause and focus on delivering value from your data. Note that enabling CloudWatch Logs integration and custom metrics incurs additional CloudWatch charges based on log ingestion volume and metric publishing frequency.

    If you have feedback or questions, reach out to your AWS account team or post on the AWS re:Post.


    About the authors

    Parul Saxena
    Parul is a Senior Big Data Specialist Solutions Architect at Amazon Web Services (AWS). She helps customers and partners build highly optimized, scalable, and secure solutions. She specializes in Amazon EMR, Amazon Athena, and AWS Lake Formation, providing architectural guidance for complex big data workloads and assisting organizations in modernizing their architectures and migrating analytics workloads to AWS.

    Ravi Kumar Singh
    Ravi Kumar Singh is a Senior Product Manager Technical-ES (PMT) at Amazon Web Services, specializing in exabyte-scale data infrastructure and analytics platforms. He helps customers unlock insights from their data using open-source technologies and cloud computing for AI/ML use cases. Outside of work, Ravi enjoys exploring emerging trends in data science and machine learning.

    Lorenzo Ripani
    Lorenzo Ripani is a Big Data Solution Architect at AWS. He is passionate about distributed systems, open-source technologies, and security. He spends most of his time working with customers around the world to design, evaluate and optimize scalable and secure data pipelines with Amazon EMR.

    Arun Prabakaran
    Arun Prabakaran is a Senior Software Engineer working at AWS. His expertise spans distributed data processing and large-scale systems. He is passionate about building reliable data platforms and enabling organizations to run analytics and AI workloads at scale.

    Jason Zou
    Jason Zou is a Software Development Engineer at Amazon Web Services, where he works on internal infrastructure supporting EMR clusters. He is passionate about building scalable, fault-tolerant distributed systems. Outside of work, he enjoys photography and playing basketball.

    Justin Mae
    Justin Mae is a Software Development Engineer on the Amazon EMR team at Amazon Web Services. He works on EMR on EC2’s control plane, building systems that improve cluster performance, observability, and operational reliability.

    Building hybrid multi-tenant architecture for stateful services on AWS

    Post Syndicated from Vasu Raj original https://aws.amazon.com/blogs/architecture/building-hybrid-multi-tenant-architecture-for-stateful-services-on-aws/

    Running a large-scale ad-serving infrastructure presents unique challenges when balancing tenant isolation with operational efficiency. Our infrastructure handles millions of requests per second and generates billions of dollars in annual advertising revenue, serving ads across multiple properties and systems.

    The cellular architecture problem

    Earlier, we had a cellular architecture where we allocated each AWS account with Application Load Balancer (ALB) and Amazon Elastic Container Service (Amazon ECS) to a given tenant. This approach provided accurate isolation but created the following significant operational challenges.

    • The scale problem: Supporting only 18 clients across four AWS Regions requires 181 separate targets. Our team configured dedicated AWS accounts, VPCs, load balancers, AWS Identity and Access Management (IAM) roles, and downstream service connections for each client.
    • The efficiency problem: Our servers spent more than 98 percent of their time waiting and less than 1 percent executing code. Average CPU utilization sat at 3 percent, and memory at 19 percent. We were paying for massive infrastructure that remained idle most of the time.
    • The onboarding problem: Bringing a new client online took approximately 52 days—roughly two weeks for AWS account provisioning, three weeks for VPC and networking setup, one week for IAM role configuration, and two weeks for downstream service integration and testing.
    • The scalability problem: When traffic grows or a new client joined, our only option is to spin up an entirely new cell and migrate to the client. We couldn’t support concurrent tier-1 live events—multiple high-value games couldn’t run simultaneously, forcing us to divert traffic to alternative systems.
    • The noisy neighbor problem: Despite our isolation efforts, we still experienced performance degradation when tenants shared infrastructure, affecting service quality and reliability.

    Why we needed dedicated compute

    Our ad-serving platform is a stateful service that loads and maintains data in memory for each tenant rather than fetching it from a database on every request. This in-memory state improves performance but creates the noisy neighbor problem when tenants share infrastructure.When two tenants share a cluster, their in-memory data competes for the same heap. A tenant with a large dataset can trigger out-of-memory conditions that affect its neighbors. This made shared-task and shared-cluster approaches challenging our stateful workloads.We needed a solution that maintained cluster-level isolation while dramatically improving operational efficiency.

    Solution overview

    We designed a hybrid multi-tenant architecture that provides cluster-level isolation within shared accounts. Here’s what we implemented:

    • Pre-integration model: Instead of provisioning VPCs, IAM roles, and downstream service connections for each new tenant, we created a configuration-driven infrastructure where these integrations are established once and reused across tenants.
    • Amazon Route 53 weighted routing: We implemented Route 53 weighted routing to enable gradual traffic migration between clusters without client-side changes. This allowed us to shift tenants between tiers as their traffic patterns evolved.
    • AWS PrivateLink connectivity: We established AWS PrivateLink endpoints that all tenants share, removing the need for us to set up new VPC peering or Transit Gateway connections for each tenant and reducing network configuration overhead by 80 percent.
    • Tier-based architecture: We organized our infrastructure into tiers (High TPS, Standard TPS, Low TPS) with multiple cells per tier, enabling horizontal scaling without the operational burden of per-tenant AWS accounts.
    • Configuration-driven onboarding: New tenant onboarding became a configuration change rather than an infrastructure provisioning exercise, dramatically reducing time and manual effort.

    The architecture is organized around three nested levels of hierarchy. A tier is the top-level grouping—a logical classification of tenants that share a common infrastructure footprint. A tier spans one or more cells, where each cell is an AWS account boundary that represents the unit of horizontal scale-out at the account level. Within each cell, one or more infra groups serve as the self-contained infrastructure unit: a VPC, an Application Load Balancer, a set of ECS clusters (one per tenant), IAM roles, and a monitoring stack.

    Why three levels? As you scale from 10 to 100 to 1,000 tenants, you will reach different AWS limits at different scales. Application Load Balancer target group limits constrain how many tenants fit in a single load balancer. AWS account limits on Elastic Network Interfaces (ENIs) and VPC endpoints constrain how many load balancers fit in a single account. This three-level hierarchy gives you two independent scaling levers to address each constraint—add infra groups to scale within an account and add cells to scale across accounts. The key design principle is that we pre-wire downstream service dependencies at tier creation, not at tenant onboarding. AWS PrivateLink connections from the tier VPC to each downstream service VPC are established after the tier is provisioned. After onboarding tenants to that tier, they automatically inherit full downstream connectivity. This single architectural decision is the primary reason for the 80 percent reduction in infrastructure setup steps. Route 53 performs weighted DNS routing across Application Load Balancers in multiple infra groups and cell accounts, enabling horizontal scale-out without client-side changes.

    The following diagram illustrates the full architecture: Route 53 distributes traffic across ALBs in multiple infra groups within a single cell account, each ALB routes to tenant-specific ECS clusters using listener rules and target groups, and the clusters share tier-level PrivateLink connections to downstream services.

    Multi-Tenant Architecture Diagram

    Figure 1: Hybrid multi-tenant architecture showing Route 53 weighted routing, Application Load Balancer listener rules, dedicated ECS clusters per tenant, and shared AWS PrivateLink connections to downstream services.

    Prerequisites

    Before you build this architecture, make sure that you have the following:An AWS account configured with least privileged permissions to create VPCs, Application Load Balancers, ECS clusters, Route 53 hosted zones, and VPC endpoints. You also need the AWS Command Line Interface (AWS CLI) version 2.x or later installed and configured with appropriate credentials. This walkthrough assumes intermediate familiarity with Amazon ECS, Application Load Balancer, and Amazon Route 53—specifically ECS task definitions, Application Load Balancer listener rules, and Route 53 routing policies. You also need at least one downstream service exposing a VPC endpoint service for AWS PrivateLink connectivity.

    Estimated time to complete: 2–3 hours.

    Walkthrough

    This walkthrough shows you how to build the previously described hybrid multi-tenant architecture. You will configure Route 53 weighted routing, deploy an ALB with tenant-specific listener rules, create dedicated ECS clusters per tenant, and establish AWS PrivateLink connectivity to shared downstream services. These will be done in a way that makes future tenant onboarding a configuration-only operation.

    Step 1: Configure Route 53 Regional endpoints with weighted routing

    Each tier exposes a single Regional DNS endpoint (for example, tier-1.us-east-1.example.com) backed by Route 53 weighted routing records. You can configure Route 53 to use weighted routing to help distribute traffic across ALBs in multiple AWS accounts. When you add a new account to the tier for horizontal scale-out, add a new weighted record. You don’t need to change existing tenant DNS entries.

    To configure Route 53 weighted routing for a tier:

    1. Open the Amazon Route 53 console and choose Hosted zones.
    2. Select or create the hosted zone for your tier.
    3. Choose Create record and select Weighted as the routing policy.
    4. Set the record name to your tier endpoint (for example, tier-1.us-east-1.example.com), record type to A, and configure an alias pointing to the ALB in your first AWS account.
    5. Set the Weight to 50 and provide a unique Set ID (for example, account-1).
    6. Enable Evaluate target health so Route 53 helps make sure that it directs traffic to healthy ALBs when you configure health evaluation.
    7. Repeat for each additional AWS account in the tier, using matching weights.

    Alternatively, run the following AWS CLI command to create the first weighted record:

    aws route53 change-resource-record-sets \
      --hosted-zone-id YOUR_HOSTED_ZONE_ID \
      --change-batch '{
        "Changes": [{
          "Action": "CREATE",
          "ResourceRecordSet": {
            "Name": "tier-1.us-east-1.example.com",
            "Type": "A",
            "SetIdentifier": "account-1",
            "Weight": 50,
            "AliasTarget": {
              "HostedZoneId": "Z35S*****K",
              "DNSName": "your-alb.us-east-1.elb.amazonaws.com",
              "EvaluateTargetHealth": true
            }
          }
        }]
      }'

    Note: Replace Z35S****K with the hosted zone ID for your ALB’s AWS Region. For more information, see Elastic Load Balancing endpoints and quotas.

    Route 53 supports up to 10,000 weighted records per hosted zone, so this approach scales to thousands of AWS accounts without architectural changes. For more information about weighted routing, see Weighted routing in the Amazon Route 53 Developer Guide.
    Step 2: Deploy an Application Load Balancer with tenant-specific listener rules

    Each infra group contains one Application Load Balancer. The load balancer inspects incoming requests and forwards them to the correct tenant’s ECS service based on a tenant identifier extracted from the request path or a custom HTTP header.

    Two Application Load Balancer quotas shape the capacity of each infra group: a maximum of 100 target groups per load balancer, and a maximum of 5 target groups per listener rule. With 20 listener rules each forwarding to 5 target groups, a single load balancer supports up to 50 tenants per infra group. With up to 5 ECS clusters per tenant, a single infra group can host up to 100 ECS clusters.

    To create a tenant-specific listener rule:

    1. Open the Amazon EC2 console and choose Load Balancers in the navigation pane.
    2. Select your Application Load Balancer and choose the Listeners tab.
    3. Choose View/edit rules for the HTTPS listener.
    4. Choose the plus (+) icon to add a new rule.
    5. Add a condition: Path is /tenant-a/* (or HTTP header if you use header-based routing).
    6. Add an action: Forward to the target group for tenant-a.
    7. Set a unique rule priority and save.

    To create the target group and listener rule using the AWS CLI:

    # Create a target group for the tenant
    aws elbv2 create-target-group \
      --name tg-tenant-a \
      --protocol HTTP --port 8080 \
      --vpc-id YOUR_VPC_ID \
      --target-type ip
    # Add a listener rule routing /tenant-a/* to the target group
    aws elbv2 create-rule \
      --listener-arn YOUR_LISTENER_ARN \
      --conditions '[{"Field":"path-pattern","Values":["/tenant-a/*"]}]' \
      --actions '[{"Type":"forward","TargetGroupArn":"YOUR_TARGET_GROUP_ARN"}]' \
      --priority 10

    For more information, see Listener rules for your Application Load Balancer.

    Step 3: Create dedicated ECS clusters per tenant

    In this step, you create a dedicated ECS cluster for each tenant within your infra group’s VPC. Use a consistent naming convention that encodes the tier, cell, infra group, and tenant identifier (for example, tier-1-cell-1-ig-1-tenant-a) to make ownership clear during operations and incident response.To create a dedicated ECS cluster for a tenant:

    1. Open the Amazon ECS console and choose Clusters.
    2. Choose Create cluster.
    3. Enter a cluster name following your naming convention (for example, tier-1-cell-1-ig-1-tenant-a).
    4. Select EC2 Linux + Networking and configure the instance type and Auto Scaling group settings appropriate for the tenant’s workload.
    5. Select the infra group VPC and subnets.
    6. Choose Create.

    To create the cluster using the AWS CLI:

    aws ecs create-cluster \
      --cluster-name tier-1-cell-1-ig-1-tenant-a \
      --region us-east-1

    In the ECS task definition for this tenant, pass the tenant identifier as an environment variable. The application reads this value at startup to scope its data access — loading only that tenant’s configuration and state from the shared remote cache:

    {
      "containerDefinitions": [{
        "name": "app",
        "image": "your-ecr-image:latest",
        "environment": [
          { "name": "TENANT_ID", "value": "tenant-a" },
          { "name": "CACHE_ENDPOINT", "value": "cache.tier-1.internal" }
        ]
      }]
    }

    Note: Replace your-ecr-image:latest with your Amazon Elastic Container Registry (Amazon ECR) image URI.

    Register the ECS service as a target in the ALB target group created in Step 2. Configure ECS service auto-scaling based on central processing unit (CPU) and memory utilization metrics, scoped to the individual service. Because each cluster is single-tenant, the ECS limit of 5,000 tasks per service applies exclusively to that tenant. One tenant’s resource consumption can’t affect another tenant’s cluster. For more information, see Creating a cluster in the Amazon ECS Developer Guide.
    Step 4: Establish AWS Private Link connectivity to shared dependencies

    This step happens at tier creation, not at tenant onboarding—and that distinction is the architectural heart of the design. For each downstream service your application integrates with, create a VPC interface endpoint in the infra group VPC. The ECS tasks in the tier route traffic to downstream services through these endpoints. Tenants onboarded to that tier can access downstream connectivity through the pre-configured endpoints.

    Each VPC interface endpoint costs approximately $7.30/month plus data transfer charges ($0.01/GB). For a tier with 50 tenants sharing one endpoint, this cost is negligible compared to the operational savings. If your downstream services are in the same VPC, consider using VPC peering or AWS Transit Gateway as lower-cost alternatives. Use AWS PrivateLink when you need to connect to services in different AWS accounts or when you require the security and isolation benefits of private connectivity.

    To create a VPC interface endpoint for a downstream service:

    1. Open the Amazon VPC console and choose Endpoints in the navigation pane.
    2. Choose Create endpoint.
    3. Select Find service by name and enter the VPC endpoint service name provided by the downstream service owner.
    4. Select the infra group VPC and the subnets used by ECS tasks.
    5. Attach a security group that allows outbound traffic from ECS tasks to the endpoint on the required port.
    6. Choose Create endpoint.

    To create the endpoint using the AWS CLI:

    aws ec2 create-vpc-endpoint \
      --vpc-id YOUR_VPC_ID \
      --service-name com.amazonaws.vpce.us-east-1.vpce-svc-YOUR_SERVICE_ID \
      --vpc-endpoint-type Interface \
      --subnet-ids subnet-*** subnet-*** \
      --security-group-ids sg-YOUR_SG_ID

    Define tier-level IAM roles with the permissions needed to access downstream services and assign these roles to ECS task definitions at the tier level. New tenants can receive the tier-level permissions through the shared IAM roles without per-tenant role creation. For more information, see Access an AWS service using an interface VPC endpoint.

    Step 5: Configure tenant isolation, scaling, and observability

    This architecture enforces tenant isolation at three layers through customer configuration. At the routing layer, ALB listener rules route traffic exclusively to the correct tenant’s target group based on the tenant identifier. ALB listener rules help route traffic to the correct tenant’s target group based on your configuration. At the compute layer, each tenant has a dedicated ECS cluster, so resource limits apply per cluster and cluster-level isolation is designed to help minimize the impact of one tenant’s resource consumption on another tenant. At the in-memory state layer, because each ECS cluster is single-tenant, in-memory data loaded at startup belongs exclusively to that tenant with no shared heap between tenants.

    Scaling strategies

    When a single tenant’s traffic grows but you haven’t reached the 50-tenant limit per infra group, use vertical scaling — it’s faster (minutes vs. hours) and doesn’t require Route 53 changes. Increase ECS task CPU and memory reservations in the task definition, or switch to larger EC2 instance types in the Auto Scaling group.

    When you’re approaching the 50-tenant limit or when multiple tenants need capacity simultaneously, add a new infra group within the same cell—a new VPC, ALB, and set of ECS clusters. Route 53 weighted routing distributes traffic across infra groups without client-side changes:

    aws route53 change-resource-record-sets \
      --hosted-zone-id YOUR_HOSTED_ZONE_ID \
      --change-batch '{
        "Changes": [{
          "Action": "CREATE",
          "ResourceRecordSet": {
            "Name": "tier-1.us-east-1.example.com",
            "Type": "A",
            "SetIdentifier": "cell-1-ig-2",
            "Weight": 50,
            "AliasTarget": {
              "HostedZoneId": "Z3******K",
              "DNSName": "your-alb-ig-2.us-east-1.elb.amazonaws.com",
              "EvaluateTargetHealth": true
            }
          }
        }]
      }'

    Use cell-level scaling only when you’re approaching account-level limits—typically after 3–4 infra groups per cell. Each AWS account has hard limits on ENIs, VPC endpoints, and other resources. When a cell approaches these limits, add a new cell by provisioning an identical tier infrastructure stack in a new AWS account and registering its ALBs in Route 53 with weighted records alongside existing cells:

    aws route53 change-resource-record-sets \
      --hosted-zone-id YOUR_HOSTED_ZONE_ID \
      --change-batch '{
        "Changes": [{
          "Action": "CREATE",
          "ResourceRecordSet": {
            "Name": "tier-1.us-east-1.example.com",
            "Type": "A",
            "SetIdentifier": "cell-2",
            "Weight": 50,
            "AliasTarget": {
              "HostedZoneId": "Z35SXDOTRQ7X7K",
              "DNSName": "your-alb-cell-2.us-east-1.elb.amazonaws.com",
              "EvaluateTargetHealth": true
            }
          }
        }]
      }'

    The tier endpoint (tier-1.us-east-1.example.com) remains stable. Tenants don’t need to update their DNS configuration as the tier grows. The following table summarizes when to use each scaling lever:

    Trigger Action Unit added
    Application Load Balancer target group limit (~50 tenants per infra group) Add an infra group within the same cell Infra group (VPC + Application Load Balancer + ECS clusters)
    AWS account-level limits (ENIs, VPC endpoints) Add a new cell Cell (new AWS account)

    Observability

    Observability is structured at two levels. Emit tenant-level metrics from each ECS service with the tenant identifier as an Amazon CloudWatch dimension. Key metrics to monitor:

    Memory usage per ECS service is the primary signal for in-memory state growth. A sudden spike often indicates a data model change or misconfigured data pipeline. Set CloudWatch alarms at 70 percent (warning) and 85 percent (critical). When memory usage exceeds 70 percent, investigate whether the tenant’s data model has changed or if a data pipeline is misconfigured. At 85 percent, prepare to vertically scale the ECS task definition. TargetResponseTime and request count per ALB target group measure latency and throughput per tenant. Establish a baseline for each tenant during onboarding (typically 100–200 ms for stateful services), then alert when latency exceeds 2x baseline for more than 5 minutes. HTTPCode_Target_5XX_Count per target group tracks error rate per tenant.For tier-level health, monitor ALB ActiveConnectionCount and ProcessedBytes, Route 53 health check status per load balancer, and ECS cluster CPU reservation and memory reservation for capacity planning. Configure Amazon CloudWatch Logs with structured log fields including tenant_id, tier_id, and region in every log entry. Use a single log group per tier with log stream prefixes that encode the tenant identifier. The following CloudWatch Logs Insights query identifies error rates by tenant across the entire tier:

    fields @timestamp, tenant_id, @message
    | filter @message like /ERROR/
    | stats count() as error_count by tenant_id
    | sort error_count desc

    Step 6: Validate the architecture

    Before onboarding production tenants, validate your architecture with the following checks:

    1. Send test requests to your tier endpoint with different tenant identifiers in the path.
    2. Verify that Route 53 distributes traffic across Application Load Balancers: aws route53 test-dns-answer --hosted-zone-id YOUR_ID --record-name tier-1.us-east-1.example.com
    3. Confirm the load balancer routes requests to the correct tenant’s ECS cluster by checking ALB access logs.
    4. Test AWS PrivateLink connectivity by making requests from ECS tasks to downstream services.
    5. Simulate a tenant memory spike by loading a large dataset and confirm that it doesn’t affect other tenants.
    6. Verify that CloudWatch metrics are being emitted with correct tenant_id dimensions.

    Results

    These results come from implementing this architecture for a stateful ad-serving application. Before this architecture, onboarding a new tenant required 52 days. With this architecture, onboarding dropped to seven days—primarily testing and validation, because infrastructure is pre-provisioned.

    Measured improvements:

    • Tenant onboarding time: from 52 days to 7 days (86 percent reduction)
    • Infrastructure setup steps per tenant: 80 percent fewer
    • Engineering effort per onboarding: 80 percent reduction
    • Feature release time: from 2–3 days to 1 day
    • Tenant capacity: up to 100 tenants per AWS account with strong cluster-level isolation

    Cleaning up

    To avoid incurring future charges, delete the resources in the following order:

    1. Deregister ECS services from target groups, then delete ECS clusters (this might take 5–10 minutes).
    2. Delete Application Load Balancer listener rules, then delete target groups associated with test tenants.
    3. Remove Route 53 weighted routing records for test tier endpoints.
    4. Delete VPC interface endpoints (AWS PrivateLink) created during tier setup.
    5. Terminate EC2 instances in Auto Scaling groups, then delete the Auto Scaling groups.
    6. (Optional) Delete the VPC if no other resources depend on it.

    Note: Deleting these resources stops charges immediately. If you plan to reuse this architecture, consider stopping ECS services instead of deleting clusters.

    Conclusion

    In this post, I showed you how to build a hybrid multi-tenant architecture that provides strong tenant isolation without requiring per-tenant AWS accounts. You learned how to configure Route 53 weighted routing to distribute traffic across multiple accounts, deploy Application Load Balancer listener rules for tenant-specific routing, create dedicated ECS clusters per tenant, and establish AWS PrivateLink connectivity to shared dependencies. This approach reduced tenant onboarding time by 86 percent and infrastructure setup steps by 80 percent.

    The most important design decision is decoupling dependency setup from tenant onboarding. Pre-wiring the PrivateLink connections, IAM roles, and remote cache endpoints at tier creation transforms onboarding from a multi-week infrastructure project into a configuration-only operation. The three-level hierarchy (tier, cell, infra group) gives you two independent scaling levers. Add infra groups when an Application Load Balancer approaches its target group limit. Add cells when an AWS account approaches its ENI or VPC endpoint limits. Route 53 weighted routing absorbs both changes transparently.

    Next steps

    Ready to implement this architecture? Here’s how to get started:

    1. Assess your current tenant distribution and identify candidates for tier consolidation.
    2. Define tier promotion criteria based on your latency and isolation requirements.
    3. Start with a single tier and 2–3 test tenants to validate the architecture.
    4. Gradually migrate existing tenants using a phased approach.
    5. Monitor tenant-level metrics for 2–4 weeks before scaling to additional tiers.

    For additional guidance, review the AWS Well-Architected Framework — SaaS Lens and explore the SaaS ECS reference architecture on the GitHub website.

    Optional enhancements

    After you’ve implemented this architecture, consider these additional improvements: formalized tier migration playbooks with automated tooling to make moving tenants between tiers a predictable, low-risk operation; and bin-packing analysis across tiers to identify tenants whose memory footprints allow co-location on the same EC2 instance without sharing a cluster, reducing EC2 costs while maintaining isolation properties.Have you implemented a similar multi-tenant architecture? Leave a comment or reach out to share your story.

    Related resources


    About the authors

    Agentic application modernization at scale with Strands and Amazon Transform custom

    Post Syndicated from Kanishk Mahajan original https://aws.amazon.com/blogs/devops/use-generative-ai-agents-for-application-modernization-at-scale-with-strands-amazon-transform-custom-and-amazon-bedrock-agentcore/

    Introduction

    Modernizing applications by upgrading language runtimes, migrating SDKs, and refactoring frameworks is important for cloud adoption but can be labor-intensive at scale. Each repository requires analysis of dependencies and transformation needs; custom transformation logic must be built and validated, and changes are often executed sequentially across codebases. If you have hundreds of applications, this stretches timelines from months to years, while introducing inconsistency across your teams.

    To address this, Amazon Web Services (AWS) provides a composable set of building blocks. AWS Transform custom enables reusable, CLI-driven code transformations for upgrading runtimes, SDKs, and frameworks consistently across large portfolios. Strands Agents provides a framework for building multi-agent systems that coordinate complex transformation workflows. Amazon Bedrock AgentCore delivers the managed runtime, memory, and observability to operate these agents reliably in production. Together, they replace manual, sequential modernization with an intelligent, automated approach that scales.

    In this post, we show you how to combine these services to build a generative AI–powered, agentic modernization system that can automatically analyze application repositories, determine required changes, create missing transformations, and execute them in parallel at scale.

    Solution overview

    The solution uses an agentic architecture that separates intelligent decision-making from deterministic execution, enabling automation at scale while maintaining consistency and control. In this post, you will build an AI-driven application modernization system that demonstrates how multi-agent workflows can be applied to large-scale code transformation scenarios. You interact with the system through a React-based frontend or API interface, submitting individual repositories or batch workloads via CSV inputs. Requests are processed asynchronously through an API layer that invokes an orchestrator agent running on Amazon Bedrock AgentCore, which coordinates specialized agents to analyze codebases, identify transformation requirements, and manage execution workflows. Results are stored and surfaced through the interface, allowing users to track progress and review outputs in real time.The workflow begins with repository analysis, where the system inspects application codebases to identify languages, dependencies, and required upgrades such as runtime version changes or SDK migrations. Based on this analysis, the system maps each application to an existing transformation when available. If no suitable transformation exists, a creation agent dynamically generates one using natural language instructions and publishes it to a centralized registry for reuse, creating a continuously improving system where transformation coverage expands over time.

    Once transformations are identified or created, an execution agent runs them at scale by invoking AWS Batch jobs that execute the AWS Transform custom CLI, enabling parallel processing across multiple repositories. The orchestrator coordinates all agents, maintains workflow state using Amazon Bedrock AgentCore Memory, and ensures reliable execution through structured task decomposition, tool invocation, and error handling. While the example focuses on application re-platforming, the same architectural pattern can be applied to other large-scale code analysis and automation workflows.

    The following architecture diagram (Figure 1) illustrates the various components of our solution as outlined in this section:architecture diagram describing the multi agent strands and agentcore deployment

    Figure 1: AWS Transform custom Agentic Orchestration Architecture using Strands agents and Amazon Bedrock AgentCore

    Prerequisites

    Complete the following prerequisites:

    1. Install the AWS Command Line Interface (AWS CLI).
    2. Install the AWS SAM CLI v1.100.0+
    3. Install Docker v20.x+.
    4. Install Node.js v18.x+
    5. Install Python v3.11+
    6. Install the AWS CDK CLI
    7. Enable access to a Bedrock model for the orchestrator in your deployment region. The default model can be configured through the Amazon Bedrock model access console. To use a different model, set `BEDROCK_MODEL_ID` in `deployment/config.env` before Step 3 and enable access to that model instead. Model access approval can take a few minutes in some accounts, so complete this step before deploying.

    Dependencies

    The Strands Agents implementation has the following dependencies that are packaged in the DockerFile:

    1. Strands multi-agent framework: strands-agents
    2. Strands agent tools and utilities: strands-agents-tools
    3. HTTP library for API calls: requests
    4. Amazon Bedrock AgentCore SDK: bedrock-agentcore
    5. AWS SDK for Python: boto3

    Deploy the solution

    The solution is available for download on the GitHub repo. This post walks through the CDK + SAM deployment path (Option A in the repository README). The repository also includes a CDK-only option (Option B); see the repository README for details.

    Step 1: Clone the repository

    git clone https://github.com/aws-samples/aws-transform-custom-samples.git

    cd aws-transform-custom-samples/agentic-atx-platform

    Step 2: Configure AWS Credentials

    # Configure AWS CLI

    aws configure

    # Verify credentials

    aws sts get-caller-identity

    Step 3: Deploy ATX CLI Container image and frontend using AWS CDK

    # Copy configuration template (defaults work for most setups; edit only to change region or Bedrock model)

    cd deployment

    cp config.env.template config.env

    # Authenticate with Amazon ECR Public (required for the Docker base image pull)

    aws ecr-public get-login-password --region us-east-1 | docker login --username AWS --password-stdin public.ecr.aws

    # Build the UI placeholder so CDK’s UI stack has ui/dist/ to deploy

    cd ../ui && npm install && npx vite build

    # Install CDK dependencies and bootstrap (run once per account/region)

    cd ../cdk

    npm install cdk bootstrap

    # Build TypeScript and deploy the three stacks

    npx tsc

    CDK_DEFAULT_ACCOUNT=$(aws sts get-caller-identity --query Account --output text)

    cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never

    # Note for accounts without a default VPC , pass the VPC context flags to `cdk deploy`:

    cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never

    cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never -c existingVpcId=vpc-xxx -c existingSubnetIds=subnet-aaa,subnet-bbb -c existingSecurityGroupId=sg-ccc

    # Subnets must be public (auto-assign public IP enabled) or private with a NAT gateway so Fargate tasks can reach Amazon ECR, Amazon S3, and Git repositories.

    Step 4: Deploy Strands Agents to AgentCore runtime using AWS SAM

    cd ../sam./deploy.sh

    # Invoke the deploy Lambda to create the AgentCore Runtime via the bedrock-agentcore-control SDK (takes 2-5 minutes)

    aws lambda invoke --function-name atx-deploy-agentcore \ --region us-east-1 \ --cli-binary-format raw-in-base64-out \ --payload '{"action":"deploy"}' \ --cli-read-timeout 900 /tmp/deploy-output.jsoncat /tmp/deploy-output.json

    Step 5: Wire the AgentCore runtime ARN into the async invoke Lambda

    ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)

    RUNTIME_ARN=$(python3 -c "import json; print(json.loads(json.load(open('/tmp/deploy-output.json'))['body'])['runtime_arn'])")aws lambda update-function-configuration \ --function-name atx-async-invoke-agent \ --region us-east-1 \ --environment "Variables={AGENT_RUNTIME_ARN=${RUNTIME_ARN},RESULT_BUCKET=atx-custom-output-${ACCOUNT_ID},JOBS_TABLE=atx-transform-jobs}"

    Step 6: Rebuild and deploy the frontend with AgentCore API endpoint

    # Update the React application with the deployed API endpoint and redeploy it.

    API_URL=$(aws cloudformation describe-stacks \ --stack-name AtxAgentCoreSAM \ --region us-east-1 \ --query 'Stacks[0].Outputs[?OutputKey==`ApiEndpoint`].OutputValue' \ --output text)

    cd ../ui

    VITE_API_ENDPOINT=$API_URL npx vite build./deploy-aws.sh

    # This rebuilds the React application with the correct API endpoint, uploads it to Amazon S3, and invalidates the Amazon CloudFront distribution.

    Step 7: Access the application

    # After deployment completes, retrieve the CloudFront distribution URL from the AWS CloudFormation outputs and open it in your browser to access the application UI.

    aws cloudformation describe-stacks \ --stack-name AtxUiStack \ --region us-east-1 \ --query 'Stacks[0].Outputs[?OutputKey==`WebsiteUrl`].OutputValue' \ --output text

    Using the application

    The UI exposes five tabs covering the complete modernization workflow: browsing available transformations, executing a transformation on a single repository, creating a new custom transformation with natural language, batch-processing a CSV of repositories, and tracking job status. This section walks through two of the most common flows.

    Create a custom transformation from natural language

    Open the Create Custom tab, describe the transformation in plain English (for example, “Upgrade Spring Boot 2 applications to Spring Boot 3”), and optionally provide a reference repository URL. The creation agent analyzes the source, generates a transformation definition, and publishes it to the ATX registry for reuse across the portfolio.

    Describing a custom transformation in plain English. The form accepts a name, description, optional reference repository, and natural-language requirements.

    Figure 2: Describing a custom transformation in plain English. The form accepts a name, description, optional reference repository, and natural-language requirements.After submitting, the orchestrator clones the reference repository, analyzes the source, and generates a transformation definition tailored to the actual code patterns found in the codebase. This takes 1–5 minutes depending on repository size. The generated definition is then shown for review in the Jobs tab, where it can be edited before publishing to the ATX registry.

    Figure 3: The AI-generated transformation definition shown for review in the Jobs tab. The agent analyzed the Flask codebase and produced a detailed definition covering routes, request handling, response patterns, and Blueprint architecture. The user can edit the definition in-place and click Publish to Registry when ready.Once published, the new transformation appears in the Transformations tab alongside AWS-managed transformations and can be executed the same way on any repository.

    Run a batch of repositories from a CSV

    Open the CSV Batch tab and upload a CSV listing repository URLs and target transformations. A sample `sample-batch.csv` is included in the repository at `agentic-atx-platform/ui/sample-batch.csv`. The preview shows the parsed rows before submission. On Submit All, each row becomes a separate AWS Batch job running in parallel, and the Jobs tab shows live status as repositories complete.

    Uploading a batch of repositories for parallel processing. The CSV lists a source repository URL, target transformation, optional validation commands, and additional plan context per row.

    Figure 4: Uploading a batch of repositories for parallel processing. The CSV lists a source repository URL, target transformation, optional validation commands, and additional plan context per row. Each row becomes an independent AWS Batch job on submission.

    Clean up

    To avoid recurring charges, remove the resources after trying the solution.

    Step 1: Delete the SAM Stack

    sam delete --stack-name AtxAgentCoreSAM --region us-east-1 --no-prompts

    Step 2: Delete the CDK Stacks

    Remove the three CDK stacks in reverse order. The S3 buckets are configured with `autoDeleteObjects: true`, so CDK will empty them before deletion.

    cd cdk

    npx cdk destroy AtxUiStack AtxInfrastructureStack AtxContainerStack --force

    Conclusion

    In this post, you learned how to build a generative AI–powered, agentic system for application modernization that can analyze application repositories, determine required code changes, create missing transformations, and execute those transformations at scale. By combining AWS Transform Custom for transformation execution with Amazon Bedrock AgentCore for orchestration, and Strands Agents for multi-agent coordination and AWS Transform container solution for parallel processing, this approach demonstrates how intelligent automation can be applied to large-scale code transformation workflows.

    This solution directly addresses the challenges of traditional modernization approaches. It reduces manual effort by automating repository analysis and transformation mapping, eliminates gaps in transformation coverage by dynamically generating reusable transformations, and significantly improves scalability through parallel execution using AWS Batch.

    By introducing a centralized, agent-driven workflow with built-in observability and state management, organizations can achieve faster, more consistent, and governed modernization across large application portfolios. To get started, deploy the solution in your AWS environment, test it with a sample repository or batch workload, and extend it by creating custom transformations tailored to your applications. You can further integrate this approach into your CI/CD pipelines to enable continuous modernization and accelerate your cloud migration initiatives.


    About the authors

    Kanishk Mahajan is Principal – AI/ML with AWS Professional Services. In this role, he leads GenAI and agentic transformations for some of AWS largest customers in Telco and Media & Entertaintment.

    Sandeep Batchu is a Senior Security Architect at Amazon Web Services, with extensive experience in software engineering, solutions architecture, and cybersecurity. Passionate about bridging business outcomes with technological innovation, Sandeep guides customers through their cloud and generative AI journey, helping them design and implement secure, scalable, and resilient architectures in the era of AI-driven transformation.

    Venugopalan Vasudeven (Venu) is a Principal Specialist Solutions Architect at AWS, where he leads Agentic AI initiatives focused on AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

    Improve DynamoDB analytics with AWS Glue zero-ETL schema and partition controls

    Post Syndicated from Raju Ansari original https://aws.amazon.com/blogs/big-data/improve-dynamodb-analytics-with-aws-glue-zero-etl-schema-and-partition-controls/

    You store transactional data in Amazon DynamoDB and get single-digit millisecond performance. However, when you want to run analytics, machine learning (ML), or reporting on that same data, you face a gap: your flexible, semi-structured DynamoDB schemas don’t align with the flat, columnar formats that analytics engines require. Bridging this gap typically means building and maintaining custom ETL pipelines, which adds development cost and operational overhead.

    AWS Glue Zero-ETL integration removes that pipeline work. It enables replication of your DynamoDB tables to Apache Iceberg tables in Amazon Simple Storage Service (Amazon S3), then query it directly with Amazon Athena. During setup, you can configure two capabilities that will shape how replicated data looks and performs: schema unnesting flattens nested attributes into individual columns, and data partitioning organizes data so your queries scan only what they need.

    In this post, you learn how to replicate Amazon DynamoDB data to Apache Iceberg tables in Amazon S3 through a zero-ETL integration. We walk through the challenges that the DynamoDB nested, schema-flexible data model introduces for analytics workloads, and show you how to configure schema unnesting and data partitioning for a sample product catalog table. We also cover how to query the replicated data in Amazon Athena using standard SQL.

    Semi-structured data meets analytics

    Your product catalog in DynamoDB contains items with nested attributes like product details, pricing tiers, and inventory information. A typical item looks like this:

    {
      "product_id": "P-1001",
      "name": "Wireless Headphones",
      "productdetails": {
        "brand": "AudioTech",
        "category": "Electronics",
        "weight_kg": 0.25,
        "specification": {
           "color": "Black",
           "storage": "128GB"
        }
      },
      "pricing": {
        "list_price": 79.99,
        "discount_pct": 10
      },
      "created_at": 1701388800000
    }

    This structure supports fast transactional reads and writes. However, when you replicate this data for analytics, you face two decisions:

    • You must decide whether to flatten nested maps like productdetails into individual columns or preserve them as-is.
    • You must choose how to organize the data on disk so that queries filtering by brand or date range scan only relevant partitions.

    With AWS Glue Zero-ETL, you address both decisions through configurable schema unnesting and data partitioning.

    Solution overview

    You replicate data from your DynamoDB table through AWS Glue Zero-ETL into Apache Iceberg tables stored in Amazon S3, then query the results with Amazon Athena. The following diagram illustrates the end-to-end architecture:

    Data flow diagram showing AWS data pipeline: DynamoDB source table → AWS Glue zero-ETL integration → Apache Iceberg on Amazon S3 → Amazon Athena analytics query.

    AWS Glue zero-ETL ingests data from Amazon DynamoDB, writes it in Apache Iceberg format to your Amazon S3 data lake, and makes it available for SQL queries in Amazon Athena—with no pipelines to build or maintain. With this integration, you:

    • Save development time by skipping custom code and ETL job management
    • Keep DynamoDB performance intact because replication doesn’t consume table’s provisioned read/write capacity
    • Get data within 15 minutes of changes in the source table
    • Query with standard tools because data lands in Apache Iceberg format, an open table format that AWS natively supports for high-performance analytics

    During setup, you configure two output settings:

    1. Schema unnesting in Zero-ETL: You choose how nested attributes appear in the target. Flattening nested maps into individual columns streamlines your queries and reduces complexity.
    2. Data partitioning in Zero-ETL: You choose how data is organized into partitions. When you filter on a partition column, the query engine reads only matching data instead of scanning everything, cutting both query time and cost.

    Schema unnesting

    When you create a zero-ETL integration, you can choose one of three unnesting options. Schema unnesting transforms complex, nested DynamoDB structures into formats that analytics engines can query directly, removing post-processing transformations.

    Each option changes how nested DynamoDB attributes appear in the target table. The right choice depends on your analytics tools and how consistent your DynamoDB schemas are.

    Option 1: No unnesting

    This option preserves the original nested structure. DynamoDB maps and lists remain as structured columns in the target.

    Using the product example, the target table retains productid and value as columns to hold DynamoDB partition key and a DynamoDB record respectively.

    Recommended for: Workloads where your analytics tools natively support querying nested data and you want to preserve the DynamoDB structure unchanged.

    Option 2: Unnest one level

    This option flattens top-level maps into individual columns. Lists remain nested.

    With this option, productdetails and pricing each become separate columns.

    Recommended for: Scenarios where your DynamoDB items have a consistent schema and you want to balance structure preservation with query simplicity.

    Option 3: Unnest all levels (default)

    This option recursively flattens nested structures using dot notation and produces the flattest schema.

    For the product table, this creates columns such as productdetails.brand, productdetails.category, productdetails.specification.color , productdetails.specification.storage , pricing.list_price, and pricing.discount_pct. The pricing map flattens similarly. Each column is directly queryable without nested access patterns.

    Recommended for: Analytics tools that prefer flat schemas when your DynamoDB items have a reasonably consistent structure. Note that deeply nested or highly variable schemas can produce very wide tables.

    Data partitioning

    You can speed up your queries and reduce costs by partitioning your replicated data. Partitioning divides data into logical segments on disk.

    When you include a filter on a partition column in your query, the query engine skips irrelevant segments entirely. This behavior is called partition pruning: instead of scanning the entire dataset, the engine reads only the data that matches your filter conditions. For large tables, partition pruning can reduce both query runtime and cost significantly.

    Default partitioning

    If you don’t specify partition columns, AWS Glue Zero-ETL partitions data using the DynamoDB primary key with bucketing. This approach supports general-purpose queries without requiring manual configuration. For specific query patterns or performance requirements, you can define custom partitioning strategies described in the subsections that follow.

    Identity partitioning

    Identity partitioning uses raw column values to create partitions. You apply this strategy to low-to-medium cardinality columns such as brand, category, or AWS Region. To partition the product table by productdetails.brand and create a separate partition for each brand, use this configuration:

    {
      "partitionSpec": [
        {
          "fieldName": "productdetails.brand",
          "functionSpec": "identity"
        }
      ]
    }

    With this setup, AWS Glue creates one partition directory per unique brand value. When you query for a specific brand, Athena reads only that partition.

    Important: Avoid identity partitioning on high-cardinality columns such as primary keys or timestamps. This creates many small partitions, which degrades both ingestion and query performance

    Time-based partitioning

    Time-based partitioning organizes data by timestamp at a chosen granularity: year, month, day, or hour. You apply this strategy to time-series data and time-range queries. To partition the product table by month on the created_at column, which stores epoch milliseconds, use this configuration:

    {
      "partitionSpec": [
        {
          "fieldName": "created_at",
          "functionSpec": "month",
          "conversionSpec": "epoch_milli"
        }
      ]
    }

    The conversionSpec parameter tells AWS Glue how to interpret the source timestamp. Supported values: epoch_sec (Unix seconds), epoch_milli (Unix milliseconds), and iso (ISO 8601 format).

    Note: The original column values remain unchanged. AWS Glue transforms only the partition column values to timestamp type in the target table

    Multi-level partitioning

    You can combine strategies for a hierarchical scheme. To partition first by month and then by brand, use this configuration:

    {
      "partitionSpec": [
        {
          "fieldName": "created_at",
          "functionSpec": "month",
          "conversionSpec": "epoch_milli"
        },
        {
          "fieldName": "productdetails.brand",
          "functionSpec": "identity"
        }
      ]
    }
    

    This scheme supports efficient queries that filter by date range, brand, or both. Place higher-selectivity columns first in the hierarchy and align the scheme with your most common query patterns.

    Best practices

    Keep these guidelines in mind when you configure your integration:

    • Avoid identity partitioning on high-cardinality columns such as primary keys, timestamps, or system-generated IDs. This leads to partition explosion and degrades performance.
    • Apply only one time-based function per column. For example, don’t partition col1 by year, month, day, and hour simultaneously.
    • Match conversionSpec to your actual data format. If your timestamps are in epoch milliseconds, use epoch_milli, not epoch_sec or iso.
    • Choose granularity based on data volume. High-volume tables benefit from finer granularity (day or hour). Lower-volume tables work well with coarser granularity (month or year).
    • Account for timezone implications with ISO timestamps. AWS Glue Zero-ETL normalizes timestamp partition values to UTC.

    Prerequisites

    To implement the AWS Glue Zero-ETL integration with a DynamoDB source, you will need:

    1. An AWS account with least privilege principle
    2. An AWS Glue database (for example, ddb_zero_etl_demo_db) with an Amazon S3 bucket associated as the database location (setup instructions)
    3. AWS Glue Data Catalog settings updated with an AWS Identity and Access Management (IAM) policy that grants fine-grained access control for zero-ETL (setup instructions)
    4. Create an IAM role named zetl-role, to be used by zero-ETL to access data from your DynamoDB table
    5. A DynamoDB source table (for example, product) configured for zero-ETL integration (setup instructions)

    Walkthrough: Create the zero-ETL integration

    Complete these steps to create a zero-ETL integration with DynamoDB as the source and Apache Iceberg tables in Amazon S3 as the target.

    Step 1: Select the source type

    1. Open the AWS Glue console.
    2. In the navigation pane, under Data Integration and ETL, choose Zero-ETL integrations.
    3. Choose Create zero-ETL integration.
    4. Select Amazon DynamoDB as the source type, then choose Next.

    AWS Glue console showing Step 1 of creating a Zero-ETL integration — selecting a source type from 14 available data sources including Amazon DynamoDB, Facebook Ads, Instagram Ads, MySQL, Oracle, PostgreSQL, and Microsoft SQL Server

    [Figure 1: Selecting Amazon DynamoDB as the zero-ETL source type]

    Step 2: Configure source and target

    1. In Source details, select your DynamoDB table (for example, product).
    2. In Target details:
      • Select the current account as target.
      • Choose the catalog and target database (for example, ddb_zero_etl_demo_db).
      • Select the IAM role (for example, zetl-role).

    AWS Glue console Step 2 — configuring source and target for a zero-ETL integration with Amazon DynamoDB "product" table as source and an AWS Glue catalog database "ddb_zero_etl_demo_db" as target

    [Figure 2: Configuring source DynamoDB table and target database]

    Step 3: Configure output settings

    1. Under Schema unnesting, select Unnest all fields.
    2. Under Data partitioning, select Specify custom partition keys.
    3. Enter the partition key (for example, productdetails.brand) and set the function to Identity.
    4. Choose Next.

    AWS Glue Zero-ETL integration output settings showing schema unnesting set to "Unnest all fields," custom partition key "productdetails.brand" configured with Identity function, and target table named "product.

    [Figure 3: Configuring schema unnesting and partition key settings]

    Step 4: Set integration details

    1. Optionally configure encryption and replication settings. The default refresh interval is 15 minutes.
    2. Enter a name for the integration (for example, ddb-zero-etl-demo).
    3. Choose Next.

    AWS Glue Zero-ETL integration Step 3 — configuring security with AWS managed KMS key, replication refresh interval set to 15 minutes, and integration named "ddb-zero-etl-demd

    [Figure 4: Configuring encryption and replication settings]

    Step 5: Review and create

    1. Review your settings and choose Create and launch integration.
    2. The integration shows as Active within about a minute.

    AWS Glue Zero-ETL integration Step 4: Review and Create — showing DynamoDB "product" table as source, Glue database "zett_target" as target with IAM role "zett-role," and partition key "productdetails.brand" with Identity function

    [Figure 5: Review and create summary]

    AWS Glue Zero-ETL Integration Details page showing "ddb-zero-etl-demo-test" integration with status "Creating," DynamoDB "product" table as source, Glue database "ddb_zero_etl_demo_db" as target, and a 15-minute refresh interval

    [Figure 6: Integration active with successful status]

    Query the replicated data

    After the integration is active and the initial replication completes (typically 15–30 minutes), you can query the data in Amazon Athena.

    Preview the replicated data

    1. Open the Amazon Athena console.
    2. In the query editor, select your target database (for example, ddb_zero_etl_demo_db).
    3. Run a preview query:
    SELECT * FROM "ddb_zero_etl_demo_db"."product"LIMIT 10;

    Verify schema unnesting

    With Unnest all fields selected, nested attributes appear as individual columns with dot notation:

    SELECT "productdetails.brand", "productdetails.category", "pricing.list_price" 
    FROM "ddb_zero_etl_demo_db"."product"
    WHERE "productdetails.category" = 'Electronics';

    Verify partition pruning

    Queries that filter on the partition column (productdetails.brand) automatically skip irrelevant partitions:

    SELECT product_id, name, "pricing.list_price"
    FROM "ddb_zero_etl_demo_db"."product"
    WHERE "productdetails.brand" = 'AudioTech';

    Amazon Athena Query Editor showing a completed SQL query selecting brand, category, and product ID from a DynamoDB zero-ETL Glue catalog table, returning two results: Samsung SmartPhone P22445 and TechCo SmartPhone P12345

    [Figure 7: Athena query to retrieve the data from Apache Iceberg lakehouse]

    You can verify the partition structure by navigating to the Amazon S3 bucket associated with your database. The data organizes into directories like:

    Amazon S3 bucket browser showing the "data/" folder in "ddb-zero-etl-demo-bucket" with two partitioned folders: "productdetails.brand=Samsung/" and "productdetails.brand=TechCo/" — confirming Iceberg partition structure from DynamoDB zero-ETL integration

    [Figure 8: Amazon S3 bucket organization for the identity partition productdetails.brand]

    Clean up

    To avoid ongoing charges, delete the resources in this order:

    1. Delete the zero-ETL integration. In the AWS Glue console, navigate to Zero-ETL integrations, select your integration, and choose Delete. Existing replicated data remains in the target, but new changes stop replicating.
    2. Delete the replicated table. In the AWS Glue Data Catalog, navigate to Tables, select the replicated table, and delete it.
    3. Delete the AWS Glue database. In the Data Catalog, select the database and delete it.
    4. Delete the Amazon S3 data. Empty and delete the S3 bucket associated with the database.
    5. Delete the DynamoDB table. If you created it for this walkthrough, delete the source table.
    6. Delete IAM resources. Remove the IAM role and policies created for the integration.

    Conclusion

    You configured schema unnesting and data partitioning for a DynamoDB zero-ETL integration, replicated a product catalog table to Apache Iceberg tables in Amazon S3, and verified the results in Amazon Athena. Unnesting flattened nested attributes into directly queryable columns. Partitioning helped the query engine skip irrelevant data, reducing both query time and cost. To take your integration further, try monitoring replication lag and data freshness with Amazon CloudWatch metrics. You can also experiment with different partitioning strategies on a staging table before applying them to production workloads, testing time-based partitioning alongside identity partitioning to find the optimal scheme for your query patterns. For broader analytics coverage, query the same Iceberg tables from Amazon Redshift Spectrum or Amazon EMR alongside Athena. For more details, explore these resources:


    About the authors

    Raju Ansari

    Raju is a Senior Software Development Engineer at AWS, specializing in building scalable, secure, serverless solutions that simplify data analytics and AI agent development. He helps organizations modernize their data analytics infrastructure and develop cutting-edge AI agentic applications. Currently, Raju focuses on building foundational AI services, including Amazon Bedrock Agents, which enable developers to create intelligent, autonomous applications at scale. Outside of work, Raju is passionate about giving back to the tech community. He actively volunteers at IEEE events and mentor early and mid-career professionals

    Shashank Sharma

    Shashank is an Engineering Leader with over 15 years of experience delivering data integration and replication solutions for first-party and third-party databases and SaaS for enterprise customers. He leads engineering for AWS Glue Zero-ETL and Amazon AppFlow, building fully managed pipelines that replicate data from sources like Salesforce, SAP, DynamoDB, and Oracle into Amazon Redshift and Apache Iceberg-based data lakes. Shashank advises startups on technology strategy and mentors engineers and technical leaders at various career stages

    How to build a cross-Region resilience for Amazon OpenSearch Service with Amazon MSK

    Post Syndicated from Sriharsha Subramanya Begolli original https://aws.amazon.com/blogs/big-data/how-to-build-a-cross-region-resilience-for-amazon-opensearch-service-with-amazon-msk/

    Cross-Region resilience for Amazon OpenSearch Service has historically been a complex challenge, relying on S3-based snapshots or cross-cluster replication that demand intricate manual failover procedures often resulting in hours of downtime, data inconsistencies, and significant lag during outages, or other operational disruptions. To overcome these limitations and help businesses stay focused on their core objectives, we’ve developed a solution that automatically maintains synchronized data across AWS Regions while supporting active-active operations in both AWS Regions.

    AWS offers two OpenSearch offerings, namely Amazon OpenSearch Service, a managed cluster-based service where you provision and manage OpenSearch domains (nodes, storage, scaling), and Amazon OpenSearch Serverless, a serverless option where AWS automatically manages infrastructure and scaling and you create collections for your search or analytics workloads. OpenSearch Service provides high availability (HA) within an AWS Region through its Multi-AZ deployment model and provides Regional resiliency with cross-cluster replication. Amazon Managed Streaming for Apache Kafka (Amazon MSK) Replicator is an Amazon MSK feature that you can use to reliably replicate data across Amazon MSK clusters in different or the same AWS Region.

    In this post, we outline the solution that provides cross-Region resiliency without needing to reestablish relationships during a fail-back, using an active-active replication model with Amazon OpenSearch Ingestion (OSI) and Amazon Managed Streaming for Apache Kafka (Amazon MSK). This solution applies to both OpenSearch Service managed clusters and Amazon OpenSearch Serverless collections. We use Amazon OpenSearch Serverless as an example for the configurations in this post.

    Solution overview

    In this solution we use Amazon MSK Replicator for bidirectional cross-Region data replication, with OSI pipelines to index data into Amazon OpenSearch Serverless collections in each AWS Region. While the S3 based approach serves the purpose, Amazon MSK Replicator provides near real-time replication with identical topic naming, which supports active-active operations. Amazon MSK Replicator provides automatic loop prevention and consumer group offset synchronization, enabling seamless cross-Region failover. You can find the code for the entire solution in the GitHub repo.

    Your architecture will follow a Regional-first approach where data sources write to a local Amazon MSK cluster within their AWS Region. In this sample deployment, an AWS Lambda function serves as the producer, streaming data into the MSK cluster. OSI pipelines consume the incoming data from the local MSK cluster and persist it to an Amazon OpenSearch Serverless collection within the same AWS Region. To achieve cross-Region data synchronization, Amazon MSK Replicator facilitates bidirectional replication between the Amazon MSK clusters, preserving the same topic names across both environments. This design validates that Amazon OpenSearch Serverless collections in each AWS Region maintain identical datasets, provides low-latency search capabilities and high availability for globally distributed workloads.

    Prerequisites

    Deploy the AWS Cloudformation template to install the prerequisites. The solution has the following prerequisite steps:

    1. Set up Amazon Virtual Private Cloud (Amazon VPC) infrastructure in both Regions
      1. Create Amazon VPCs with private subnets in at least two or three Availability Zones for high availability at the AWS Region level
      2. Configure Network Address Translation (NAT) Gateways for outbound internet access from private subnets
      3. Use non-overlapping CIDR blocks
    2. Establish Amazon OpenSearch Serverless collections in both AWS Regions
    3. Create Amazon OpenSearch Serverless Collections for log analytics
    4. Configure encryption, network, and data access policies
    5. Create Amazon VPC endpoints for private access
    6. Configure MSK clusters in both AWS Regions
    7. Enable AWS Identity and Access Management (IAM) authentication (SASL/IAM)
    8. Enable Multi-VPC connectivity (required for Amazon MSK Replicator and OSI)
    9. Configure MSK cluster policies to allow kafka.amazonaws.com and osis-pipelines.amazonaws.com service principals
    10. Configure IAM permissions for pipeline and replication access
    11. Create IAM roles for the OSI pipelines with permissions to access Amazon Managed Streaming for Apache Kafka and Amazon OpenSearch Serverless.
    12. Create IAM roles for the Amazon MSK Replicator with permissions for cross-Region access to Amazon Managed Streaming for Apache Kafka clusters.

    This AWS CloudFormation template helps you in deploying all of the required configurations with primary AWS Region as us-east-1 and secondary AWS Region as us-west-2.

    The following snippets shows the configuration for the OSI pipeline, which writes data from Amazon MSK to Amazon OpenSearch Serverless. The OSI pipeline uses MSK as a source with IAM authentication.

    version: "2"
    kafka-pipeline:
    source:
    kafka:
    acknowledgments: true
    topics:
    - name: "opensearch-data"
    group_id: "osi-consumer-group-primary"
    aws:
    msk:
    arn: "arn:aws:kafka:us-east-1:<aws-acccount-id>:cluster/production-msk-primary/CLUSTER_ID"
    region: "us-east-1"
    sts_role_arn: "arn:aws:iam::<aws-acccount-id>:role/production-osi-pipeline-primary-role"
    sink:
    - opensearch:
    hosts:
    - "https://<OPENSEARCH_SERVERLESS_COLLECTION_ID>.us-east-1.aoss.amazonaws.com"
    index: "application-logs-${yyyy.MM.dd}"
    aws:
    serverless: true
    region: "us-east-1"
    sts_role_arn: "arn:aws:iam::<aws-acccount-id>:role/production-osi-pipeline-primary-role"
    dlq:
    s3:
    bucket: "production-opensearch-dlq-us-east-1"
    region: "us-east-1"
    sts_role_arn: "arn:aws:iam::<aws-acccount-id>:role/production-osi-pipeline-primary-role"

    The OSI pipeline IAM Role has the required permission for Amazon MSK and Amazon OpenSearch Serverless to consume message data from the source and write data to the destination. For true active-active replication, sample deploys two Amazon MSK Replicators in each AWS Region. Each Amazon MSK cluster requires cluster policy to allow Amazon MSK Replicator and OSI to connect. To validate the bidirectional replication, the solution uses AWS Lambda functions to produce test messages to both Amazon MSK clusters.

    When an application generates an event, it first publishes the message to an Apache Kafka topic in the Regional streaming cluster powered by Amazon Managed Streaming for Apache Kafka. In this sample deployment, an AWS Lambda function simulates application activity by producing events into the topic. These events are durably stored in the Apache Kafka partitions, providing a reliable buffer between producers and downstream consumers. An ingestion pipeline built using Amazon OpenSearch Ingestion continuously reads the event stream from the Apache Kafka topic and prepares the data for indexing. The pipeline then indexes the processed events into a collection in Amazon OpenSearch Serverless, making the data searchable in near real time.

    At the same time, Amazon MSK Replicator replicates the Apache Kafka topic to a peer Amazon MSK cluster in a secondary AWS Region while preserving the topic structure. This makes the same event stream available in the secondary AWS Region without requiring changes to downstream consumers. An OpenSearch Ingestion pipeline in the secondary AWS Region consumes the replicated topic and indexes the events into its local OpenSearch Serverless collection. As events continue to flow through the system, both AWS Regions maintain synchronized datasets that can be queried independently. This architecture enables low-latency Regional search while maintaining a resilient, cross-Region copy of the indexed data.

    Failover scenario and considerations

    You can failover your application to the Amazon OpenSearch Serverless collection in the other AWS Region and continue operations without interruption. The data present before the impairment is available in both collections. Upon recovery, Amazon MSK Replicator and OSI pipelines automatically resume operations without manual intervention. Data that you write to the healthy AWS Region during the impairment is automatically backfilled to the recovered AWS Region. For detailed step-by-step guidance, see disaster recovery section in GitHub repo.

    When using Amazon MSK Replicator, be aware that cross-Region data transfer incurs additional costs. To help verify reliability, configure Dead Letter Queues (DLQ) for OSI pipelines to capture failed document ingestion. Additionally, monitor essential Amazon CloudWatch metrics including ReplicationLatency for tracking lag between clusters, DocumentsFailed for identifying ingestion issues, and MessagesInPerSec for observing message throughput.

    Persistent buffering in OSI provides a built-in safety net that prevents data loss when data producers send information faster than your OpenSearch cluster can process it, removing the need to provision and manage separate buffering infrastructure. By using managed storage across multiple Availability Zones, this feature enhances data durability while dynamically allocating OpenSearch Compute Units (OCUs) for both buffering and data processing, which incurs additional costs. Persistent buffering isn’t enabled by default. Without it, the OSI pipeline relies on an in-memory buffer, which is volatile and has limited capacity for storing incoming data before processing.

    Conclusion

    In this post, we showed you how to achieve cross-Regional resiliency for Amazon OpenSearch Serverless and OpenSearch Service managed clusters. In our experiments, most writes of a few KBs of data completed within one to a few seconds between the two chosen AWS Regions. Replication lag between the AWS Regions depends on network delay between chosen Regions and the settings configured on Amazon Opensearch Ingestion (OSI) pipeline.

    Refer to AWS Service Level Agreements (SLAs) and Amazon Opensearch Ingestion (OSI) for more details. You can also achieve active-passive replication for OpenSearch using OSI and Amazon Simple Storage Service (Amazon S3) as mentioned in another post Achieve cross-Region resilience with Amazon OpenSearch Ingestion.


    About the authors

    Sriharsha Subramanya Begolli works as a Senior Solutions Architect with AWS, based in Bengaluru, India. His primary focus is assisting large enterprise customers in modernising their applications and developing cloud-based systems to meet their business objectives. His expertise lies in the domains of data, analytics and generative AI.

    Qais Poonawala is a Senior Technical Account Manager at AWS Enterprise Support, India, who specializes in Cloud Operations and Security while helping customers architect highly scalable, resilient, and secure solutions. With extensive experience in enabling enterprise customers across AWS services, he has a passion for solving complex challenges and developing solutions around Security, Cloud Operations, and GenAI.

    Jay Jothi is a Senior Technical Account Manager based in Chennai, India, where he supports major enterprise customers in maximizing the benefits of cloud technology. With extensive experience in the financial services industry and a specialization in Cloud Operations, he focuses on helping financial clients manage data efficiently, derive actionable insights using GenAI, and deliver cost-effective solutions.

    Building an end-to-end agentic SRE using AWS DevOps Agent

    Post Syndicated from Ray Hodges original https://aws.amazon.com/blogs/devops/building-an-end-to-end-agentic-sre-using-aws-devops-agent/

    Introduction

    As modern applications evolve into complex ecosystems of serverless functions, microservices, and event-driven architectures, incident response becomes increasingly challenging. DevOps and SRE teams spend hours manually correlating data across observability tools and troubleshooting issues, racing against SLA deadlines. This reactive firefighting drains productivity, degrades reliability, and delays innovation.

    AWS DevOps Agent provides an opportunity to shift how teams achieve operational excellence. As an autonomous, always-on frontier agent, it investigates incidents the moment they occur, identifies root causes by correlating telemetry across your ecosystem, and recommends specific mitigation plans, all without constant human intervention. On-call engineers wake up to a root cause, instead of active incidents. AWS DevOps Agent supports multi-cloud and hybrid environments, not just AWS-native architectures.

    This blog post demonstrates how to build an end-to-end agentic SRE solution using AWS DevOps Agent. You learn how to configure DevOps Agent Spaces that define an investigation scope, integrating seamlessly with Amazon CloudWatch, Splunk, GitHub, and Slack. It further demonstrates automated incident trigger using webhooks, and AWS DevOps Agent integration with custom tools by creating a custom MCP agent. The agent investigates issues by analyzing patterns across multiple data sources, providing root cause, and then generates detailed mitigation plans that can be implemented via a coding agent. By the end, you will have a deployed frontier agent that acts as a true extension of your team. One that works persistently, scales massively, and delivers complete operational outcomes while freeing your engineers to focus on innovation rather than firefighting.

    Architecture

    Architectural diagram showing the setup used in this AWS DevOps Agent deployment.

    Implementation

    This implementation spans three specialized AWS accounts with distinct responsibilities.

    The Demo Application account hosts the production infrastructure being monitored. The CI/CD pipeline integrates GitHub via AWS CodePipeline for automated deployments, while an Application Load Balancer distributes traffic and monitors health. The observability layer leverages Amazon CloudWatch alarms to detect anomalies, Amazon EventBridge to route events, and AWS Lambda as a webhook handler that forwards incident notifications to AWS DevOps Agent.

    The account named Splunk provides centralized log aggregation and analysis. An Amazon EC2 instance hosts the Splunk Log Collector, while Splunk MCP manages the centralized control plane. A VPC peering connection establishes secure, private network connectivity between the Demo Application and Splunk account VPCs, enabling seamless log forwarding, without internet exposure.

    AWS DevOps Agent account contains the autonomous investigation engine. AWS DevOps Agent receives incident webhooks from the Demo Application account, orchestrates autonomous investigations across integrated data sources, correlates telemetry from CloudWatch, Splunk, and GitHub, generates mitigation plans, and coordinates the incident response. The webhook integration provides communication, receiving incident triggers from Lambda, and sending investigation updates to Slack for real-time team collaboration.

    Data flow: When an incident triggers the CloudWatch alarm, EventBridge invokes a Lambda function that, in turn, invokes the DevOps Agent webhook with a payload. The agent triggers an investigation based on its native troubleshooting capabilities. For a comprehensive view of the incident, it queries Splunk logs via MCP, retrieves deployment history from GitHub, and correlates CloudWatch metrics with deployment events to build application topology understanding. It analyzes temporal relationships between deployments and operational incidents, identifies root causes, and generates detailed mitigation plans with specific remediation steps, success criteria, and rollback procedures via Splunk MCP. The DevOps Agent’s runbooks/skills guide its investigation from start to finish, keeping it on track and aligned with established SRE procedures. Investigation results and recommendations are posted to Slack, enabling on-call engineers to wake up to identified root cause, instead of active incidents.

    Creating your agentic DevOps engineer

    DevOps Agent Spaces

    A DevOps Agent Space defines the tools and infrastructure that AWS DevOps Agent has access to. Each Agent Space contains your AWS account configurations, third-party tool integrations, and access permissions. See Best Practices for Deploying AWS DevOps Agent in Production for detailed information describing the DevOps Agent spaces.

    Creating an Agent Space can be done through the console, or via AWS Command Line Interface (AWS CLI). You should name your Agent Space with a descriptive name to identify its purpose. For example, if your application is “WidgetMaker”, then you can name your Agent Space “WidgetMaker Agent” to help you quickly identify the context of that agent.

    Follow the steps in Creating an Agent Space for details and considerations when creating an Agent Space.

    Agent Space webhooks

    Before connecting any services to your DevOps Agent Space, make sure to create the webhook for your Agent Space. The schema for you to send messages to your Agent Space is shown below:

    { 
    eventType: ‘incident’; 
    incidentId: string; 
    action: ‘created’ | ‘updated’ | ‘closed’ | ‘resolved’; 
    priority: “CRITICAL” | “HIGH” | “MEDIUM” | “LOW” | “MIMIMAL”; 
    title: string; 
    description?: string; 
    timestamp?: string; 
    service?: string; 
    //The original event generated by service is attached here. 
    data?: object; 
    }
    

    You can find great examples on the Invoking DevOps Agent through Webhook page. When creating a secure connection for this blog, we used HMAC (Hashbased Message Authorization Code). Optionally, you can experiment with the CloudWatch Alarm Webhook Integration from Git.

    {
    import { createHmac } from "node:crypto"; 
    function sendEventToWebhook() { 
       const payload = { 
          eventType: "incident", 
          ... // other event data 
        }; 
    const timestamp = new Date().toISOString(); 
    const hmac = createHmac("sha256", secret); 
    hmac.update(`${timestamp}:${JSON.stringify(payload)}`, "utf8"); 
    const signature = hmac.digest("base64"); 
    fetch(webhookUrl, { 
       method: "POST", 
       headers: { 
          "Content-Type": "application/json", 
          "x-amzn-event-timestamp": timestamp, 
          "x-amzn-event-signature": signature, 
        }, 
        body: JSON.stringify(payload), 
      }); 
    }

    Finally, you create the webhook.

    Screenshot of the "Create a webhook to trigger investigations for your agent space" form.

    Make sure you download and save this unique url and secret key. Once you move on from this screen, you will no longer be able to see the secret. Now that we’ve created the webhook endpoint, we will set up the alarm or choose an existing alarm. Then we will use an Amazon Simple Notification Service (Amazon SNS) topic as the Alarm Action and subscribe a Lambda function to this topic. The Lambda function then calls the webhook. Store the webhook URL in Lambda environment variables for security.

    The CloudWatch flow is: CloudWatch Alarm → Amazon EventBridge → Lambda → DevOps Agent Webhook.

    Test by forcing the alarm into the ALARM state and verifying the DevOps Agent receives the event. See some samples on sending these alarms via WebHook at the aws-samples github.

    Splunk Integration

    For Splunk integration, you will need to perform a few tasks on your Splunk server. First, you will need to enable the Splunk MCP Server to expose the MCP URL for AWS DevOps Agent.

    For Splunk MCP Server, you will first configure a token to allow AWS DevOps Agent to securely log into the Splunk MCP server.

    Note: You will need to have a role called ‘mcp_user’ (it doesn’t need any capabilities) and add it to the user account in Splunk that you are going to create the token in the next step.

    Screenshot of Splunk MCP Server configuration form.

    The audience should default to ‘mcp’ on this screen, but if not, audience will need to be ‘mcp’. Remember, you must copy the token from the screen when you create the token, or you will not be able to access it after you close the screen, requiring you to create a new token. Then, you can validate that the endpoint is active and copy the endpoint url. Note, the url presented reflects the url that you are using for the Splunk management console. If you have created a listener on port 8089 with a different url, for example, https://splunkmcp.yoururl.com:8089, then you will need to replace the url shown (https://splunkadmin.yoururl.com) with the proper url.

    Screenshot showing Splunk's MCP Server endpoint.

    Finally, copy the MCP Configuration for use in AWS DevOps Agent. Note, just as above, validate that the url is the same as the listener you have created. Also, reminder to replace <Your Token> with the bearer token you’ve created (and copied) above.

    Screenshot showing Splunk MCP configuration.

    To configure Splunk to send alerts to AWS DevOps Agent to begin investigations, you will need to use Better Webhooks because the default Splunk webhook does not support headers nor authentication.

    Once you have Better Webhooks, you can create a credential and choose Custom HTTP Header. Name can be whatever you desire, but we used “DevOpsAgentBearer” to be descriptive.

    Header Name: Authorization

    Header Value: “Bearer thetokenyousavedwhenyoucreateddevopsagentwebhook”
    (Include “Bearer” and a space before your token from your DevOps Agent webhook)

    Screenshot showing Splunk's A Better Webhooks credential configuration form.

    You can skip the advanced section and save your credential.

    Now, you can configure the alert for your error state by finding it in search and saving search as an alert. Under Trigger Actions, select Add Actions and choose Better Webhook from the menu.

    Screenshot showing the creation of an alert in Splunk.

    Then, format the message body as shown in AWS DevOps Agent.

    { eventType: ‘incident’; 
    incidentId: string; 
    action: ‘created’ | ‘updated’ | ‘closed’ | ‘resolved’; 
    priority: “CRITICAL” | “HIGH” | “MEDIUM” | “LOW” | “MIMIMAL”; 
    title: string; 
    description?: string; 
    timestamp?: string; 
    service?: string; 
    //The original event generated by service is attached here. 
    data?: object; 
    }

    In Splunk, the URL is the DevOps Agent webhook url which you had saved in a .csv with your token while creating the webhook. Paste the format above into the Body Format section as shown below, select the credential you saved in Better Webhooks earlier, and save your alert.

    Screenshot showing formatting the body of your alerts from Splunk to DevOps Agent in the Splunk alerts form.

    Notice that the Body Format box should reflect the format from AWS DevOps Agent above. Now, AWS DevOps Agent will initiate an investigation when Splunk errors exceed the threshold for the alert you’ve created. You may want to experiment with throttling and thresholds to keep AWS DevOps Agent from starting too many investigations.

    Connecting to Slack

    You can connect AWS DevOps Agent to your Slack environment and configure a channel for your Agent Space to communicate with. You can have multiple Agent Spaces communicate in one Slack channel, or you can have existing Slack channels for your SRE team invite the Agent Space to it.

    To get started, you need to have access to a Slack workspace with the ability to install and authorize third-party applications. You then need to go to the AWS DevOps Agent console, navigate to “Settings” and select “Communications”. When you choose Register, you will be redirected to Slack to authorize the AWS DevOps Agent application for your workspace. It is important to install at the workspace level, not in your enterprise grid.

    After you choose Allow, you will be directed back to your DevOps Agent console to associate your Agent Space with your Slack channel. Go to your Agent Space, scroll down to Communications, and choose Add integration.

    Screenshot showing the configuration of communication in DevOps Agent.

    Towards the bottom of the popup, you should see Slack and it should show “Registered” in green.

    Screenshot showing Slack being registered in DevOps Agent.

    Choose Add and follow the instructions in the window to obtain and insert your channel ID into the DevOps Agent Space.

    Screenshot showing how to connect an Agent Space Slack.

    Once completed, you just need to add the AWS DevOps Agent to your channel by typing the following into your Slack channel: /invite @AWS DevOps Agent

    Now, you can start an investigation, and the AWS DevOps Agent will provide details in your channel.

    Connecting GitHub to AWS DevOps Agent

    Screenshot showing the configuration screen in DevOps Agent to connect to GitHub.

    Screenshot with further details to configure your GitHub connection in DevOps Agent.

    GitHub integration is a two-step process. First, register GitHub at the AWS account level: navigate to your Agent Space’s Capabilities tab, select Add under Pipeline, choose GitHub, and complete the OAuth flow to install the AWS DevOps Agent GitHub app. You can select which repositories the app can access — all or a specific subset. Once registered, connect repositories to individual Agent Spaces by selecting the relevant repos under the Pipeline section. The GitHub app requests read-only access and receive deployment events, enabling the agent to correlate code changes with operational incidents.

    DevOps Agent Skills

    You can use DevOps Agent Skills to define a set of rules for all investigations to follow, guiding the Agent to use certain documentation, or telemetry sources for certain types of data. Skills are self-contained directories containing Markdown instructions that provide specialized capabilities to AWS DevOps Agent. AWS DevOps Agent supports a subset of the Agent Skills specification — an open standard for packaging agent instructions and resources—supporting only non-executable documents: Markdown instructions, PDFs, images, and data files. For example, if your environment uses Dynatrace for alarms and metrics, Splunk for logs, and CloudWatch for serverless logs, create a skill to accelerate issue resolution. You create these Skills in your Operator console by selecting the Skills section on the lower left side of the screen. You can then either review your existing skills or use the Add skill button to choose between Create skill and Upload skill options.

    Screenshot showing the Skills definition page in the DevOps Agent Operator console.

    The documentation on DevOps Agent Skills should help you with the schema and best practices in creating these skills.

    Investigate root cause

    Now that you have everything connected to your DevOps Agent Space, you can interact with the AWS DevOps Agent you’ve created. You can investigate anomalies in your environment, or have alarms trigger your Agent to begin an investigation on its own and provide updates in your Slack channel and the Operator console. You can also ask the agent to provide health summaries, suggest preventive maintenance, and other SRE tasks you would do throughout the lifecycle. You can do this in the operator console and simply type your question into the Chat with DevOps Agent box. For example, “What is causing high CPU usage on my EC2 instances starting an hour ago?” and the AWS DevOps Agent will begin investigating your request.

    Screenshot of the DevOps Agent Operator Console to initiate a chat with a DevOps Agent.

    While optional, the steps below can help speed up a particular investigation and help track multiple investigations. Adding an Investigation starting point can help speed up the investigation by telling the agent to check a particular alarm, or an Autoscaling Group (ASG), or even a specific set of instances where you are seeing increased CPU usage. This guides the investigation to start with data sources pertaining to these resources, instead of looking at all your telemetry to find anomalies to start investigating.

    Screenshot showing the Investigation starting point text box to help guide an investigation in DevOps Agent.

    You should also make a habit of assigning a meaningful name to your investigations, so that you can look at the historical data with some context.

    Screenshot showing the Name your investigation input in DevOps Agent Operator Console.

    Generating mitigation plan

    A mitigation plan is a set of actionable steps that AWS DevOps Agent produces to resolve an identified incident. After the agent publishes a root cause under the Root Cause tab, select “Generate mitigation plan” to create a structured remediation plan. Alternatively, automate this step using the AWS CLI — use aws devopsagent create-backlog-task to trigger investigations and update-backlog-task to approve mitigation plans programmatically. By automating this step, you can integrate mitigation plan generation directly within their incident workflow, without having to leave their incident management application. The CLI returns the mitigation steps back into the integrated app or system. Each plan follows four phases: Prepare, Pre-Validate, Apply, and Post-Validate. Within each phase, the agent provides suggested actions with commands to update infrastructure-as-code templates or make configuration changes. It also generates agent-ready specs compatible with coding agents like Kiro for implementation.

    Screenshot showing the "Generate mitigation plan" button in DevOps Agent Operator Console.

    Agent-ready Spec and fix implementation

    An agent-ready spec is a structured set of instructions that AWS DevOps Agent generates within a mitigation plan, designed to be consumed directly by a coding agent. When the mitigation plan includes code-level fixes — such as updating infrastructure-as-code templates or application logic — AWS DevOps Agent produces these specs alongside the suggested actions. To apply a fix, copy the agent-ready spec and hand it off to a compatible coding agent like Kiro. The coding agent interprets the spec and implements the required changes in your codebase. This creates a seamless handoff from incident diagnosis to code remediation, closing the loop between identifying a root cause and deploying the fix without manually translating mitigation steps into code changes.

    Screenshot showing the "Agent-ready spec" screen in DevOps Agent console.

    Conclusion

    In this post, we demonstrated building an end-to-end agentic SRE solution using AWS DevOps Agent — from configuring Agent Spaces and integrating CloudWatch, Splunk, GitHub, and Slack, to triggering automated investigations via webhooks, generating mitigation plans, and handing off agent-ready specs to coding agents like Kiro for implementation. Together, these capabilities shift incident response from reactive firefighting to autonomous resolution, reducing MTTR from hours to minutes while freeing your engineers to focus on innovation.

    Get started today:

    Author Bios

    Photo of Manik Chopra, one of the authors

    Manik Chopra

    Manik Chopra is a Principal Technical Account Manager at AWS. He helps customers adopt AWS services and provides guidance in various areas around Generative AI, Data Analytics and Optimization. His areas of expertise include delivering solutions using Amazon Bedrock, AWS DevOps Agent, Amazon QuickSight, Amazon Athena, and various other automation techniques. Outside of work, he enjoys spending time outdoors and traveling.

    Photo of Ray Hodges, one of the authors

    Ray Hodges

    Ray Hodges is a Senior Technical Account Manager at Amazon Web Services, where he’s been guiding some of the world’s largest enterprises through their cloud journeys. Ray partners with Fortune 100 customers — most notably, a large financial institution — to drive transformative outcomes in operational resilience, observability modernization, and enterprise-scale cloud operations. Ray leads many operations and resiliency efforts. Prior to AWS, Ray built 25+ years of enterprise IT expertise as an Enterprise Architect at Atos and Senior Architect at IBM, where he led large-scale private cloud implementations and pioneered PaaS delivery models. He is an AWS Certified Solutions Architect Professional, and brings deep cross-domain expertise spanning architecture, security, operations, and service management — all with a relentless focus on driving resilient business outcomes through technology.

    Photo of Sheng Liao, one of the authors

    Sheng Liao

    Sheng Liao is Sr. TAM Manager at Amazon Web Services, where she leads a team of Technical Account Managers dedicated to AWS’s largest and most complex strategic accounts. With a focus on cloud operations, AI/ML adoption, and enterprise architecture, Sheng works closely with senior technical leaders to accelerate cloud transformation at scale. Her team has driven impactful outcomes including GenAI-powered analytics in production processing millions of transactions monthly, early adoption of autonomous DevOps tooling that reduced incident response times to minutes, and large-scale observability modernization initiatives. Sheng is a strong advocate for bringing AWS thought leadership directly to customers, championing programs like AI/ML Developer Lifecycle sessions that have engaged hundreds of engineers and architects. Prior to her current role, Sheng built extensive experience across cloud infrastructure and enterprise technology.

    How to consolidate cross-Region S3 data into OpenSearch

    Post Syndicated from David Venable original https://aws.amazon.com/blogs/big-data/how-to-consolidate-cross-region-s3-data-into-opensearch/

    You might have data in Amazon Simple Storage Service (Amazon S3) buckets in different AWS Regions that you want available in a single Amazon OpenSearch Service domain or collection. Consolidating data across Regions provides unified analytics and searches, reduce operation complexity, and streamline your search infrastructure. We’re happy to announce that Amazon OpenSearch Ingestion pipelines can now read from S3 buckets in different Regions to ingest and consolidate data into a single OpenSearch Service domain or collection.

    To consolidate this data across AWS Regions, you previously had to provide your own solution. Now Amazon OpenSearch Ingestion can help you accomplish this. In this post, I’ll show you how to use the new cross-Region support to ingest data from S3 buckets across multiple AWS Regions into a single OpenSearch Service domain or collection.

    Amazon OpenSearch Ingestion (OSI) is a feature-rich data ingestion pipeline that you can use for many different purposes: observability, analytics, and zero-ETL search. Many customers use OpenSearch Ingestion to ingest data from Amazon S3 into OpenSearch Service domains and Amazon OpenSearch Serverless collections. Until now, you could only ingest from a single AWS Region at a time. Now that you can use OpenSearch Ingestion for cross-Region S3 ingestion, I’ll show you how you can use it in two scenarios: batch processing using S3 scan, and streaming ingestion using Amazon Simple Queue Service (Amazon SQS) queues for AWS vended logs like Amazon Virtual Private Cloud (Amazon VPC) Flow Logs and AWS CloudTrail.

    Prerequisites

    Complete the following prerequisite steps:

    1. Deploy an OpenSearch Service domain or OpenSearch Serverless collection in the Regions where you want to perform your search or analytics.
    2. You need S3 buckets in at least two different Regions. You can use existing ones or create S3 buckets. You can use one in the same AWS Region as your OpenSearch Service domain or collection, or use two completely different Regions.
    3. Upload objects with data into your S3 buckets. The data can be JSON, ND-JSON, Parquet, CSV, or plaintext formats.
    4. Configure AWS Identity and Access Management (IAM) permissions needed for OSI. For instructions, see Amazon S3 as a source.
    5. For cross-Region ingestion, you must now also include the s3:GetBucketLocation permission. This gives the pipeline the ability to determine which AWS Region the bucket is located in.

    After you complete these steps, you can either set up your Amazon OpenSearch Ingestion pipelines for batch or streaming scenarios. In the following sections, I’ll give you recommendations on when to choose which approach, and I outline the steps for creating your pipeline.

    Batch scenarios

    You can use the OpenSearch Ingestion S3 scan capability to read batch data from S3. You might find this approach useful when your data is written to S3 on a schedule. To perform a cross-Region S3 scan, you only specify the buckets that you’re reading from when you create the OpenSearch Ingestion pipeline.

    The following diagram shows the design for an OpenSearch Ingestion pipeline in us-west-2 reading from S3 buckets in us-east-1 and eu-west-1 and writing that data into an OpenSearch Service domain in us-west-2.

    Next, you will create an OpenSearch Ingestion pipeline. You must create this pipeline in the same Region as your OpenSearch Service domain or collection.

    version: "2"
    s3-scan-cross-region:
      source:
        s3:
          compression: automatic
          codec:
            json:
          scan:
            buckets:
              - bucket:
                  name: amzn-s3-demo-bucket1
              - bucket:
                  name: amzn-s3-demo-bucket2
          aws:
            region: us-west-2
    
      sink:
        - opensearch:
            hosts: [ "https://search-mydomain-abcdefghijklmn.us-west-2.es.amazonaws.com" ]
            index: s3_scan_cross_region
            aws:
              region: us-west-2
    

    The previous pipeline configuration supports the JSON codec. You might want to configure a different codec if your data isn’t a large JSON object.

    You can now query your OpenSearch Service domain or collection to see the data that you ingested.

    Streaming scenarios: AWS vended logs

    Like many of our customers, you might want to ingest S3 data from different AWS Regions into OpenSearch Service. A common reason is to consolidate AWS vended logs. For example, VPC Flow Logs, CloudTrail data, and load balancer logs. For these scenarios, you can configure OpenSearch Ingestion pipelines to read from an Amazon SQS queue to stream data into your OpenSearch Service domain or collection.

    These AWS vended logs write to Amazon S3 in the same AWS Region as the service running it. For example, VPC Flow Logs will be in the same AWS Region as your Amazon VPC. You can use OpenSearch Ingestion to consolidate these logs into one AWS Region. In the VPC Flow Logs example, you can consolidate your VPC Flow Logs from multiple AWS Regions into a single OpenSearch Service domain or collection to analyze network patterns from your different Amazon VPCs.

    The following diagram outlines the overall setup. It shows an example of sending AWS vended logs from us-east-1 and eu-west-1 to an OpenSearch Service domain in us-west-2. You can change the AWS Regions depending on your specific needs.

    1. You must configure your vended logs to write log events to Amazon S3 buckets in their respective AWS Regions. Using VPC Flow Logs as our example, you can configure VPC Flow Logs for your VPCs.
    2. Create an Amazon SQS queue in the same AWS Region as your OpenSearch Service domain.
    3. Amazon S3 doesn’t send notifications to cross-Region Amazon SQS queues, so you will use intermediate Amazon Simple Notification Service (Amazon SNS) topics to consolidate the notifications from multiple Regions into one queue. For each S3 bucket, create an SNS topic.
    4. Configure S3 Event Notifications for SNS. You will do this for each S3 bucket and each SNS topic.
    5. SNS can send cross-Region notifications to SQS. Create a subscription from each SNS topic that you created in step 3 to the single SQS queue you created in step 2.
    6. Configure your pipeline role to read from SQS and read from the relevant S3 buckets.

    Now create an OpenSearch Ingestion pipeline in the same AWS Region as your OpenSearch Service domain.

    version: "2"
    s3-sqs-cross-region:
      source:
        s3:
          notification_type: sqs
          codec:
            newline:
          sqs:
            queue_url: https://sqs.us-west-2.amazonaws.com/123456789012/amzn-s3-demo-all-regions
          aws:
            region: us-west-2
    
      sink:
        - opensearch:
            hosts: [ "https://search-mydomain-abcdefghijklmn.us-west-2.es.amazonaws.com" ]
            index: s3_sqs_cross_region
            aws:
              region: us-west-2
    

    The previous pipeline configuration supports the JSON codec. You might want to configure a different codec if your data is not a large JSON object.

    Next, upload objects with data into your S3 buckets. By uploading data, S3 will send notifications to SNS and then the SQS queue.

    You can now query your OpenSearch Service domain or collection to see the data that you ingested.

    Here is what makes this possible and what is different. The SQS queue receives the event notifications for the buckets. Before the cross-Region feature of OpenSearch Ingestion, the pipeline could see these events, but couldn’t access the S3 bucket even if the permissions were granted. Now, the pipeline will determine the AWS Region that the bucket is in, access an AWS Security Token Service (AWS STS) token for the AWS Region of the bucket. Using the STS token from the same Region as the S3 bucket allows the pipeline to read and access the data.

    Using the AWS Console

    When you create the pipeline using the OpenSearch Ingestion console, you will have options to select a blueprint for your use-case. These blueprints help you create pipelines for various vended log types only by selecting your SQS queue and OpenSearch domain. The blueprint handles the data type mappings for you by including appropriate processors. You can use these blueprints as a starting point and modify your processors for your specific requirements.

    Clean up resources

    When you’re done testing this out, use the following resources to delete the resources that you created.

    If you set up a batch pipeline:

    • Delete the OpenSearch Ingestion pipeline.

    If you set up a streaming pipeline:

    For both pipelines, these steps help you delete the common resources.

    Conclusion

    In this post, I showed you how you can use Amazon OpenSearch Ingestion to ingest data from Amazon S3 buckets in different AWS Regions. I showed that this works for both batch scan and streaming scenarios. The feature offers you a straightforward way to consolidate your data from other Regions into one OpenSearch Service domain or collection.

    To get started with the cross-Region S3 source, refer to the OpenSearch Ingestion documentation or try creating a pipeline from one of our blueprints using the OpenSearch Ingestion console. You can read about the codecs that OpenSearch Ingestion offers for parsing your S3 objects. You can also learn how about the various processors that OpenSearch Ingestion offers, so you can transform and enrich your data to meet your needs.

    You can also use OpenSearch Ingestion for cross-Region and cross-account. To do this, you must grant cross-account permissions on your S3 bucket. You must also make some changes to your pipeline configuration. Combining what I showed you in this post with the existing cross-account features greatly expands your ingestion options.

    If you’re ready to take your streaming ingestion analytics to the next level you can read about how to generate metrics from logs and even how to send those derived metrics to Amazon Managed Service for Prometheus.

    Have you tried out the cross-Region capabilities of OpenSearch Ingestion? Share your use-cases and questions in the comments.


    About the authors

    David is a senior software engineer working on observability in OpenSearch at Amazon Web Services. He is a maintainer on the Data Prepper project.

    Build streaming applications on Amazon Managed Service for Apache Flink with AI-assisted guidance

    Post Syndicated from Mazrim Mehrtens original https://aws.amazon.com/blogs/big-data/build-streaming-applications-on-amazon-managed-service-for-apache-flink-with-ai-assisted-guidance/

    Building production-ready Apache Flink applications requires learning a complex ecosystem. The learning curve is steep for newcomers, and even experienced Flink developers encounter complexity when scaling applications or troubleshooting production issues. With the new Kiro Power and Agent Skill for Amazon Managed Service for Apache Flink, you can get AI-assisted guidance for building, improving, and migrating streaming applications directly in your development environment, with recommendations that are grounded in best practices.

    The Managed Service for Apache Flink Kiro Power and Agent Skill helps you navigate challenges across the Flink application lifecycle. For new development, the tool provides contextual guidance on application architecture, state management patterns, and connector selection. For existing application improvements, it analyzes your existing code to identify performance bottlenecks, reliability risks, and opportunities for improvement. If you’re upgrading from Apache Flink 1.x to 2.x, it detects compatibility issues and provides targeted refactoring steps to modernize your applications.

    In this post, we walk through installing the Power and Skill, using Amazon Kinesis Data Streams to build a Kinesis Data Stream-to-Kinesis Data Stream streaming pipeline, and migrating an existing application to Flink 2.2. You can follow along with this use case to see how the Managed Service for Apache Flink Kiro Power can help you build a resilient, performant application grounded in best practices.

    Solution overview

    The Managed Service for Apache Flink Power/Skill works across multiple AI development tools, providing the same comprehensive guidance in each:

    • Kiro: Installs as a Power that automatically activates for Flink-related development activities
    • Cursor and Claude Code: Installs as an Agent Skill following the open Agent Skills standard
    • Other compatible agents: Compatible with tools supporting the Agent Skills specification

    The Power/Skill provides guidance across the development lifecycle:

    • Best practices for Managed Service for Apache Flink application development
    • Maven dependency management and project structure
    • Resource improvements including KPU sizing, parallelism tuning, and checkpointing
    • Job graph architecture patterns and anti-patterns
    • Amazon CloudWatch monitoring and logging configuration
    • Flink 1.x to 2.2 migration guidance with state compatibility assessment
    • Connector-specific guidelines

    The content is maintained in a single repository with use case specific entry points that are dynamically loaded depending on your needs.

    Prerequisites

    To use the tool, you need:

    • A development machine running macOS, Linux, or Windows with Java 11 or later (Java 17 for Flink 2.2) and Apache Maven installed
    • One of the following AI development tools:
      • Kiro IDE
      • Cursor
      • Claude Code
      • Other Agent Skills-compatible tools
    • Basic knowledge of Java and stream processing concepts (helpful but not required)
    • An AWS Identity and Access Management (IAM) role configured with access to create and run Managed Service for Apache Flink applications, create Amazon Simple Storage Service (Amazon S3) buckets for Flink application dependencies, create Kinesis Data Streams for streaming, and create IAM roles (required if deploying an application)

    Installation

    Installing as a Kiro Power

    1. Open Kiro IDE.
    2. Open Amazon Managed Service for Apache Flink and select Open in Kiro.

    1. Choose Install to install the power.

    1. Verify that the power is listed in the installed powers in the Kiro IDE.

    The Power is now installed and automatically activates when you work on Flink-related development activities.

    Installing as an Agent Skill

    Agent Skills are discovered automatically by compatible tools through the SKILL.md file. Installation varies by tool:

    Per-project installation (available in one project):

    # For Cursor
    git clone https://github.com/awslabs/managed-service-for-apache-flink-agent-steering-files.git .cursor/skills/flink
    
    # For Claude Code
    git clone https://github.com/awslabs/managed-service-for-apache-flink-agent-steering-files.git .claude/skills/flink
    
    # For other Agent Skills-compatible tools
    git clone https://github.com/awslabs/managed-service-for-apache-flink-agent-steering-files.git .agents/skills/flink

    Personal installation (available across projects):

    # For Cursor
    git clone https://github.com/awslabs/managed-service-for-apache-flink-agent-steering-files.git ~/.cursor/skills/flink
    
    # For Claude Code
    git clone https://github.com/awslabs/managed-service-for-apache-flink-agent-steering-files.git ~/.claude/skills/flink

    To verify the installation, interact with the skill in your preferred tool. In Claude Code, you can invoke it with /flink. In Cursor, type / in Agent chat and search for flink. For more information about Agent Skills, see the Agent Skills documentation.

    Example: Building a Kinesis-to-Kinesis streaming pipeline

    Rather than listing best practices, the Power/Skill actively guides you through making the right architectural decisions at each stage of development.

    The following walkthrough demonstrates building a Flink application that reads from Amazon Kinesis Data Streams, analyzes events, and writes to another Kinesis stream. To follow along, run the same prompts in your Kiro IDE or other development tool. In the following prompts, we focus on local development and don’t create AWS resources. However, if you prompt the agent to create and deploy AWS resources, they will incur additional costs.

    Starting the conversation

    In the Kiro IDE, we can open a new chat in Vibe mode and prompt: “Help me build a Flink application that reads from Kinesis, processes events with windowed aggregations, and writes results to another Kinesis stream”:

    Kiro chat showing a prompt to build a Kinesis streaming application

    What happens next

    The AI assistant loads relevant guidance and walks you through the development process:

    1. Confirm project requirements and details

    Kiro automatically loads the Power based on the context of your prompt. The assistant then asks you questions about your use case to make sure that it builds the right application for your needs:

    For the demo, we can prompt for a financial services use case: “I’m in financial services, so let’s use that as the use case. Try calculating volatility in real-time. And let’s use Flink 1.20 for now.”.

    Kiro then confirms its assumptions and asks to proceed:

    2. Project setup

    After we confirm, Kiro generates a project with Flink 1.20 dependencies, Kinesis connectors, and proper scope configuration for Managed Service for Apache Flink deployment. The assistant creates the application structure with proper configuration separation between local development and Managed Service for Apache Flink service-level settings. Then, it creates a Kinesis source with proper deserialization and the sink with partitioning strategy, and windowed aggregation logic with proper state management, TTL configuration, and error handling.

    Generated project structure with Flink dependencies and Kinesis connectors

    Kiro also compiles the code to verify that it builds correctly. We can then proceed by asking Kiro to help us with running the application locally for testing.

    3. Testing the project locally

    You can run the application locally to test the results. We can prompt: “Can we run this locally using something like LocalStack to test deploying the job and also see some example results?”

    Kiro creates the necessary Docker resources, testing scripts, and deployment steps to run the application locally with synthetic resources. If it encounters bugs or detects issues during the local testing process, it fixes them so that your deployment runs smoothly:

    Kiro creating Docker resources and local testing infrastructure

    We can also access our local Flink UI to view our application:

    Local Flink UI showing the running streaming application

    4. Deploying the application to Managed Service for Apache Flink

    Now that our application is running and generating results end-to-end, we can use the Power for other tasks. For example, you can get guidance on KPU allocation and parallelism settings based on your expected throughput, configure monitoring with CloudWatch metrics, logging, and dashboards for operational visibility, or set up infrastructure as code (IaC) for deploying in Managed Service for Apache Flink. We can prompt: “This is great! Can you help me deploy this application to Managed Service for Apache Flink? I’d like to use CloudFormation for deployment.”

    Kiro conversation summarizing creation of CloudFormation deployment resources

    Using the generated AWS CloudFormation templates and deployment scripts, we can deploy our application to AWS with associated resources for Kinesis Data Streams, Amazon S3 buckets for application JAR files, CloudWatch log groups, and IAM roles. Deploying these resources requires IAM credentials with associated permissions and will incur cost for the associated resource usage.

    In a traditional workflow, you build your application, deploy to Managed Service for Apache Flink, then discover performance issues or configuration problems in production. You spend time debugging checkpoint failures, serialization errors, or resource bottlenecks.With the Power/Skill, the AI assistant catches these issues during development. When you need complex aggregation and processing logic, it helps you to do so in a way that uses resources efficiently with Flink’s scaling model. When you create an application bug that would cause a crash in production, it helps you identify it early with local end-to-end testing. The Power is configured with guidance and best practices to help with the development process from start to finish.

    Example: Migrating to Flink 2.2

    The Managed Service for Apache Flink Kiro Power and Agent Skill provide contextual advice specific to your situation. For new developers, it walks through the complete workflow from project setup to deployment, explaining Managed Service for Apache Flink-specific concepts along the way. For migration projects, it analyzes your existing code for Flink 2.2 compatibility issues and provides targeted refactoring guidance. The following example shows how the tool helps with the complex task of migrating from Flink 1.x to 2.2.

    1. Assessing migration compatibility

    We can ask Kiro to help us upgrade our project from the previous example to Flink 2.2: “I need to migrate my Flink 1.x application to 2.2. Can you help me identify compatibility issues?”

    The assistant loads the Managed Service for Apache Flink Kiro Power and analyzes our code to identify potential issues:

    Kiro analyzing Flink 1.x code for 2.2 compatibility issues

    In this case, using our generated project on Flink 1.20, Kiro identified the following compatibility issues for the upgrade:

    • Java 11 must move to Java 17 (minimum for Flink 2.2)
    • Flink version 1.20.3 must update to 2.2.0
    • The Kinesis connector must update from 5.1.0-1.20 to 6.0.0-2.0
    • Time references must change to java.time.Duration in window and lateness calls
    • The LocalStreamEnvironment instance of check must be removed (class removed in 2.2)
    • The isEndOfStream() override must be dropped from PriceTickDeserializer (method removed)
    • implements Serializable must be added to PriceTick and VolatilityResult

    It also verified that some parts of the project are already Flink 2.2 compatible. The project uses the new Source Sink V2 APIs, the logging is 2.2 ready, the POJOs with no collection fields are state migration safe, and there are no Kryo registrations or TimeCharacteristic usage.

    2. Implementing the migration

    We can then ask Kiro to provide a step-by-step migration plan, both for updating the code and deploying to Managed Service for Apache Flink: “Can you help me update the application for Flink 2.2, and help me figure out the steps to upgrade my running Managed Service for Apache Flink application?”

    Kiro evaluates the entire application code base. It evaluates it against the Power’s migration guidance and best practices, and provides a comprehensive analysis of the breaking changes, risks, and potential issues that would arise in the upgrade. After we approve the changes, Kiro then proceeds to make the necessary updates to make our application compatible with Flink 2.2 and provide us with a step-by-step upgrade process for the running application:

    Kiro providing a step-by-step migration plan for Flink 2.2

    Now that Kiro has prepared the application for Flink 2.2, highlighted migration risks, and provided us with a clear path to execute the upgrade, you can test the upgrade process with confidence. From here, we can proceed to run our Flink 2.2 application locally, test the upgrade process in a development environment in Managed Service for Apache Flink, and then execute the upgrade in our production environment. If we run into issues, we can return to the Kiro Power to get advice, resolve issues, and unblock our upgrade.

    Cleanup

    To remove the Power/Skill installation:

    For Kiro:

    1. Open Kiro IDE.
    2. Navigate to the Powers tab.
    3. Uninstall the Amazon Managed Service for Apache Flink Power.

    For Agent Skills:

    # Remove per-project installation
    rm -rf .cursor/skills/flink  # or .claude/skills/flink
    
    # Remove personal installation
    rm -rf ~/.cursor/skills/flink  # or ~/.claude/skills/flink
    If you created Managed Service for Apache Flink applications or associated resources during development, clean the resources up:
    1. Delete the Managed Service for Apache Flink application from the AWS Console.
    2. Remove associated resources for sources and sinks, if created for development.
    3. Delete CloudWatch log groups if no longer needed.

    Conclusion

    In this post, we showed you how the Kiro Power and Agent Skill for Amazon Managed Service for Apache Flink brings AI-assisted development to stream processing. You can use the tool to overcome Flink’s learning curve, build applications following Managed Service for Apache Flink best practices, and migrate to Flink 2.2 with confidence. To get started, choose the path that fits your workflow:

    • If you use Kiro, install the Power from the Powers tab and start a new chat with a Flink-related prompt.
    • If you use Cursor, Claude Code, or another Agent Skills-compatible tool, clone the GitHub repository into your skills directory and reference the steering/ files for guidance.
    • If you are new to Amazon Managed Service for Apache Flink, review the Amazon Managed Service for Apache Flink Developer Guide and the Apache Flink documentation to build foundational knowledge alongside the Power/Skill.

    We welcome your feedback. Report issues or request features through GitHub Issues, or contribute improvements via pull requests.


    About the authors

    Mazrim Mehrtens

    Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

    Five ways to use Kiro and Amazon Q to strengthen your security posture

    Post Syndicated from Roger Nem original https://aws.amazon.com/blogs/security/five-ways-to-use-kiro-and-amazon-q-to-strengthen-your-security-posture/

    A Monday morning security alert flags unauthorized access attempts, security group misconfigurations, and AWS Identity and Access Management (IAM) policy violations. Your team needs answers fast.

    Security teams are using Kiro and Amazon Q Developer to handle repetitive tasks—scanning resources, drafting policies, and researching Common Vulnerabilities and Exposures (CVEs)—so engineers can focus on risk decisions and complex scenarios that require human judgment, resulting in faster threat response and more consistent security coverage.

    This post shows you five ways to use Kiro and Amazon Q Developer to strengthen your AWS security posture based on the AWS Well-Architected Framework Security Pillar. Each technique builds on a common foundation described after the tool overview below.

    About these tools

    Amazon Web Services (AWS) gives customers choices when it comes to AI-assisted development and security automation. Whether you prefer Kiro’s agentic integrated development environment (IDE) experience or the deep integration of Amazon Q Developer into your existing AWS environment, both tools can help you implement the security practices described in this post. The right choice depends on your team’s workflow, and in many cases both tools are complementary and can be used together.

    Kiro is an AI-powered, agentic, IDE designed by AWS for specification-driven development, combining natural language prompting with structured, intentional coding to generate, test, and deploy applications.

    Amazon Q Developer is the generative AI assistant integrated into AWS development and cloud environments, designed to answer questions, generate code, troubleshoot issues, and automate operational tasks across AWS services.

    For setup instructions and to learn more, see the Kiro documentation and Amazon Q Developer documentation.

    1. Embed security best practices with persistent context

    Providing AI assistants with the right context helps them produce more consistent and relevant results. Each of the five techniques in this post becomes significantly more powerful when your AI assistant already understands your organization’s security standards. Setting up persistent context first means every subsequent interaction builds on that foundation, and the results you get from triage, remediation, reviews, and policy development will better reflect your specific environment rather than generic best practices.

    Without persistent context, you need to repeat the same security requirements in every prompt such as "enable encryption, use least privilege IAM settings, and enable logging," which leads to inconsistent results and missed controls. Amazon Q Developer IDE Plugin rules and Kiro steering files (CLI and IDE) solve exactly this problem: you can use them to codify your organization’s security standards so AI automatically builds secure infrastructure consistently, without requiring you to repeat requirements in every prompt. Both tools support this capability independently, so you can configure whichever fits your workflow, or use both together for coverage across your full development environment. The following steps show you how to get started with each.

    For Amazon Q Developer:

    1. Create directory: .amazonq/rules/ in your project root.
    2. Create file: .amazonq/rules/security-standards.md.
    3. Paste your organization’s security standards in natural language (see “Example security standards context file” below).

    For Kiro (steering files):

    In Kiro, persistent context documents are called steering files. They give the agent ongoing awareness of your architecture decisions, coding standards, and security requirements across every interaction and every session.

    1. Create file: security-standards.md in your project root.
    2. Reference it in prompts: Using security-standards.md as context, create....

    Pro tip: You can use Kiro itself to help you create steering files. Describe your security requirements in natural language and ask Kiro to generate a structured steering file for your review before saving and activating it. This means your AI assistant can help you build the very context it will later use, making the setup process faster and more thorough.

    Example security standards context file:

    # AWS Security Standards
    
    ## Identity and Access Management
    - All IAM roles must use least privilege principles
    - Require MFA for console access
    - Enable IAM Access Analyzer for all accounts
    - Rotate access keys every 90 days
    - Use IAM roles for EC2 instances, never embed access keys
    
    ## Data Protection
    - Enable encryption at rest for all storage services (S3, EBS, RDS)
    - Use AWS KMS customer-managed keys for sensitive data
    - Enable encryption in transit with TLS 1.2 minimum
    - Implement S3 bucket policies denying unencrypted uploads
    - Enable versioning and MFA delete for critical S3 buckets
    
    ## Infrastructure Protection
    - Security groups must follow least privilege (no 0.0.0.0/0 on sensitive ports)
    - Deploy resources in private subnets when possible
    - Enable VPC Flow Logs for network monitoring
    - Use AWS WAF for public-facing applications
    - Implement Network ACLs as additional defense layer
    
    ## Detective Controls
    - Enable CloudTrail in all regions with log file validation
    - Configure CloudWatch alarms for security events
    - Enable GuardDuty for threat detection
    - Set up AWS Config rules for compliance monitoring
    - Implement centralized logging with retention policies
    
    ## Incident Response
    - Create SNS topics for security alerts
    - Configure automated responses with AWS Lambda
    - Maintain runbooks for common security incidents
    - Enable AWS Systems Manager for secure instance access
    - Implement automated backup and recovery procedure

    What this unlocks:

    Without persistent context, a prompt like Create a Lambda function to process customer data could produce a basic function with no encryption, logging, or IAM configuration. AI output is non-deterministic, meaning that without guidance it might or might not include those controls. Steering files and rules documents minimize those variables by providing stronger guidance as part of every prompt and inference input.

    With your security standards embedded as in the example above, however, the same prompt generates a function with KMS-encrypted environment variables, a CloudWatch log group with 90-day retention, least-privilege IAM, VPC placement in private subnets, a dead-letter queue, and AWS X-Ray tracing—all automatically.

    Where it works:

    This persistent context approach applies across both tools and all infrastructure generation workflows:

    • Amazon Q Developer IDE Plugin: Rules in .amazonq/rules/ apply automatically to every code generation and review interaction.
    • Kiro: Steering files provide the agent with continuous architectural and security awareness across sessions and projects.

    The shift-left impact:

    This approach isn’t a replacement for your existing continuous integration and delivery (CI/CD) security automation. It’s a powerful complement to it, and that distinction matters. By embedding security standards directly into the development workflow, you shift security validation further left than pipeline checks can reach. Developers across your organization, not just security specialists, can generate infrastructure that meets your security standards from the first line of code. This scales security expertise into non-security roles, empowers development teams to self-serve on compliance requirements, and reduces the volume of findings that ever reach your automated pipeline checks.

    The result is security functioning as an enabler of faster development rather than a gate that slows it down, and security engineers spending their time on policy design and complex risk decisions rather than remediating avoidable misconfigurations.

    Measurable impact:

    Track these metrics to quantify the value of persistent context:

    • Security findings during code review: Establish a 30–60 day baseline before enabling context files, then compare
    • Time from development to deployment: Track average cycle time before and after
    • Remediation cost: Research consistently shows defects fixed in development cost significantly less than those fixed in production. Track your own ratio for 60 days
    • Standards consistency: Audit a random sample of infrastructure pull requests for compliance with your top 10 policies

    Implementation recommendation: Start by codifying your top 10 most frequently violated security policies as context. Measure the reduction in these specific findings over 30–60 days to quantify the impact on your team.

    2. Accelerate security finding triage and investigation

    AWS Security Hub consolidates findings from services such as Amazon GuardDuty, AWS Config, Amazon Inspector, and third-party security tools into a single dashboard, providing centralized security finding visibility and built-in triage capabilities across your AWS environment. AWS Security Hub Extended will bring even more capabilities into this mix, giving customers expanded control and additional opportunities to leverage the AI-assisted workflows described in this post at greater scale and with deeper integration across your security toolchain.

    Kiro can complement Security Hub by helping you correlate findings across accounts, understand CVE context, and develop remediation approaches, including:

    • Query findings using natural language across multiple AWS accounts and AWS Regions
    • Understand specific CVEs and their potential impact on your infrastructure
    • Generate investigation queries for AWS CloudTrail and Amazon Virtual Private Cloud (Amazon VPC) Flow Logs
    • Correlate security events across different time periods and services
    • Access the latest AWS security documentation and best practices

    How it works – Model Context Protocols:

    To enable these capabilities, Kiro uses Model Context Protocols (MCPs)—a standardized way for AI assistants to securely connect with external tools, services, and data sources, enabling them to take actions, retrieve real-time information, and interact with APIs beyond their built-in capabilities.

    Open source MCP servers for AWS are a suite of specialized MCP servers that enable Kiro to interact with AWS security services, providing real-time visibility into your security posture. To get started, configure security-focused MCP servers in your Kiro settings file (as shown in the following example). For full instructions on configuring MCP servers in Kiro, see the Kiro MCP documentation.

    Note on authentication: Before querying Security Hub, verify you have configured valid AWS credentials for the target account. Set the AWS_PROFILE value to a named profile in your ~/.aws/credentials file that has the appropriate permissions, or configure credentials using the AWS Command Line Interface (AWS CLI) (aws configure). Without valid credentials for the target account, Kiro will not be able to retrieve findings.

    {
        "mcpServers": {
            "awslabs.aws-api-mcp-server": {
                "command": "uvx",
                "args": ["awslabs.aws-api-mcp-server@latest"],
                "env": {
                    "FASTMCP_LOG_LEVEL": "ERROR",
                    "AWS_PROFILE": "<PROFILE>",
                    "AWS_REGION": "us-east-1"
                },
                "timeout": 120000,
                "disabled": false
            },
            "awslabs.cloudtrail-mcp-server": {
                "command": "uvx",
                "args": ["awslabs.cloudtrail-mcp-server@latest"],
                "env": {
                    "FASTMCP_LOG_LEVEL": "ERROR",
                    "AWS_PROFILE": "<PROFILE>"
                },
                "disabled": false
            },
            "awslabs.iam-mcp-server": {
                "command": "uvx",
                "args": ["awslabs.iam-mcp-server@latest"],
                "env": {
                    "FASTMCP_LOG_LEVEL": "ERROR",
                    "AWS_PROFILE": "<PROFILE>"
                },
                "disabled": false
            }
        }
    }

    Configure the following security-focused MCP servers to get started:

    • AWS API MCP Server: Interact with Security Hub, GuardDuty, IAM Access Analyzer, and AWS Config through AWS CLI commands
    • CloudTrail MCP Server: Audit trail analysis and compliance monitoring
    • AWS IAM MCP Server: Manage IAM users, roles, policies, and permissions
    • AWS Knowledge MCP Server: Access up-to-date AWS security documentation and best practices

    For a full list of available MCP servers, see the awslabs/mcp GitHub repository.

    Example: querying Security Hub with Kiro:

    1. Open your terminal or Kiro IDE.
    2. Enter the following command:
    "Show me all critical security findings from Security Hub in my production account ID <ACCOUNT ID>"

    Example output:

    > Found 4 critical security findings in account 123456789012:
    
    ## Configuration Issues (2)
    
    1. SSM.7 - SSM documents block public sharing disabled
    - Status: FAILED (since July 17, 2025)
    - Impact: Systems Manager documents can be publicly shared
    - Remediation: Enable block public sharing setting for SSM documents
    - [Documentation](https://docs.aws.amazon.com/console/securityhub/SSM.7/remediation)
    
    2. Config.1 - AWS Config not properly configured
    - Status: FAILED (since March 4, 2025)
    - Issue: Config isn't recording required IAM resource types (User, Role, Group, Policy)
    - Standards affected: CIS, NIST 800-53, PCI DSS, AWS Foundational Security
    - Remediation: Enable recording for IAM resources in AWS Config
    - [Documentation](https://docs.aws.amazon.com/console/securityhub/Config.1/remediation)
    
    ## Vulnerabilities (2)
    
    3. CVE-2020-36242 in Lambda function: MyLambdaOne
    - Package: cryptography version 3.2.1
    - CVSS Score: 9.1 (Critical)
    - Issue: Integer/buffer overflow in Fernet encryption class
    - Fix: Upgrade to cryptography 3.3.2
    - Function: SPC-1233HH5R-MyLambdaOne-lUh3ESH0MdXF
    
    4. CVE-2020-36242 in Lambda function: AutoUpdateMyLambdaOne
    - Package: cryptography version 3.2.1
    - CVSS Score: 9.1 (Critical)
    - Same vulnerability as above
    - Function: SPC-1233HH5R-AutoUpdateMyLambdaOne-d9HIBfxThbFW

    Real-world impact:
    Security finding triage that previously required navigating multiple consoles, correlating logs manually, and researching CVE databases can be accelerated significantly. Teams that have integrated AI-assisted triage into their Security Hub workflows report reducing mean time to triage for critical findings from hours to minutes, enabling faster containment and more consistent coverage across accounts.

    3. Accelerate remediation of security findings in your infrastructure as code

    AI assistants can scan your infrastructure code and flag security issues with specific fix recommendations. However, implementing these changes requires careful review, testing, and validation before any changes reach production.

    Important: AI-generated remediation suggestions must be reviewed by a qualified security engineer before implementation. Automated application of AI-generated changes without human validation can introduce unintended misconfigurations or service disruptions. Treat AI output as a starting point, not a finished product.

    The workflow:
    You can execute this workflow in either Kiro or Amazon Q Developer, depending on which tool fits your existing development environment:

    1. Ask Kiro or Amazon Q Developer to scan your infrastructure files and identify security gaps.
    2. Review AI-generated remediation suggestions with your security team.
    3. Test changes in non-production environments.
    4. Validate using AWS security services such as IAM Access Analyzer, AWS Config, and Security Hub.
    5. Deploy to production with monitoring and rollback procedures in place.

    Example prompt:

    "Scan my infrastructure at /path/to/templates, identify all S3 buckets without encryption, enable AES-256 encryption, add bucket policies to deny unencrypted uploads, and provide the deployment command"

    What happens:

    The AI assistant analyzes your infrastructure files, whether written in AWS CloudFormation, Terraform , or AWS Cloud Development Kit (AWS CDK), and identifies resources that violate security best practices. It then implements controls such as encryption at rest using AWS Key Management Service (AWS KMS) or Amazon Simple Storage Service (Amazon S3)-managed keys, adds bucket policies enforcing encryption in transit, configures public access blocks, and generates the exact deployment command with a change preview so you can review what will be modified before anything is applied.

    Based on the example security standards context file above, the following controls would be applied across all generated infrastructure: encryption at rest and in transit, least-privilege IAM policies, security group optimizations, VPC configurations, logging enablement, and backup and recovery settings.

    Validation required:
    AI-generated configurations deserve the same thoughtful review as other infrastructure code. Even a policy that looks correct on the surface might need tuning to match your organization’s least-privilege standards, or encryption settings might need adjusting to satisfy specific compliance requirements. Running those changes through a non-production environment and having a human confirm the results before anything reaches production are part of good infrastructure practices, whether the code was written by a person or generated by AI.

    Real-world impact:

    Identifying non-compliant resources across multiple accounts manually can take many hours and generating remediation templates for each resource can add significant time. Security teams that have adopted AI-assisted infrastructure scanning report spending less time on manual identification and template generation, and with AI assistance the same identification and drafting work can be completed in much less time. Customers report that a full remediation cycle that previously occupied their team for the better part of a day can be completed in under an hour when AI handles the scanning and template generation. It is worth noting that manual remediation time grows considerably at scale, as remediating dozens of non-compliant resources is not a linear exercise. Validation time in non-production environments remains essential regardless of how the remediation was generated, and should always be factored into your planning.

    4. Perform in-depth security reviews

    Amazon Q Developer and Kiro can analyze your infrastructure code and identify potential security issues across multiple categories aligned with the AWS Well-Architected Framework Security Pillar.

    Using Amazon Q Developer:

    1. Open your infrastructure file in your IDE.
    2. Select the code you want to review.
    3. Open the context menu and choose Send to Amazon Q, then choose Optimize.
    4. Select Focus on security best practices.

    Using Kiro:

    1. Open your infrastructure file in Kiro.
    2. Enter a natural language prompt such as: Perform a comprehensive security review of this CloudFormation template and identify all deviations from our standards.
    3. Kiro will automatically apply your steering files as additional context when generating its response.
    4. Review the findings and iterate with follow-up prompts.

    Security categories evaluated: For the complete, up-to-date list of security categories and controls, see the AWS Well-Architected Framework Security Pillar documentation. Current categories include but are not limited to:

    • Identity and access management: Overly permissive IAM policies, missing multi-factor authentication (MFA) requirements, unused credentials and access keys, cross-account access risks
    • Detective controls: CloudTrail logging configuration, Amazon CloudWatch alarm coverage, GuardDuty enablement status, and AWS Config rule implementation
    • Infrastructure protection: Security group misconfigurations, public subnet exposure, missing AWS WAF rules, unencrypted network traffic
    • Data protection: Storage encryption status, KMS key rotation policies, backup configurations, S3 bucket access controls
    • Incident response: Amazon Simple Notification Service (Amazon SNS) alerting setup, log retention policies, automated response mechanisms

    Example output:

    Security Recommendations:
    - Enable S3 bucket encryption with KMS: Critical
    - Implement least privilege IAM policies: High
    - Enable GuardDuty threat detection: High
    - Configure VPC Flow Logs: Medium
    - Add WAF rules for API Gateway: Medium
    - Enable CloudTrail in all regions: Critical
    - Implement automated backup policies: High
    
    Total security improvements: 23 findings across 5 Well-Architected pillars

    Keeping your configuration files current:

    A security architect review remains valuable for keeping your steering files and rules documents complete and current. The goal is an AI assistant that already understands your environment, not one that needs correcting after every interaction. Treat your configuration files as living documents and update them when your security standards evolve, when new services are adopted, or when post-incident reviews reveal gaps. As this post notes, project rules reduce architectural drift and help maintain consistency as AI agents operate more autonomously.

    Real-world impact:

    Security reviews that previously required a security engineer to manually inspect infrastructure templates line by line can be completed in significantly less time with AI assistance. Teams using AI-assisted security reviews as a pre-commit gate—before code reaches CI/CD pipeline checks—report catching a meaningful portion of security findings earlier in the development cycle where they are faster and less costly to address. Integrating this review step into pull request workflows means security validation happens continuously rather than only at deployment gates.

    5. Assist with service control policy development

    You can use AWS Organizations Service Control Policies (SCPs) to apply preventive controls consistently across every account in your organization, enforcing security baselines without relying on individual account administrators. Kiro can generate initial SCP drafts from natural language security requirements, speeding up the drafting and iteration process considerably. Because SCPs are preventive controls that can’t be bypassed by administrators, misconfigurations can cause organization-wide service disruptions, making expert validation and staged testing essential before any SCP reaches production.

    Step 1: Generate an SCP draft:

    Describe your security requirements in natural language:

    "Create an SCP with these security controls:
    - Deny creation of S3 buckets without encryption
    - Require MFA for IAM user console access
    - Prevent public RDS snapshots
    - Deny security group rules allowing 0.0.0.0/0 on sensitive ports
    - Enforce encryption for all EBS volumes
    - Require VPC Flow Logs on all VPCs
    - Deny IAM policy creation without approval tags
    - Restrict resource creation to approved regions only"

    Kiro generates a complete SCP policy JSON with proper deny statements, condition keys for MFA and encryption enforcement, resource-level restrictions, and regional compliance requirements.

    Step 2: Validate and lint the SCP:

    Use Kiro or Amazon Q Developer to assist with policy linting and initial testing as a first layer of validation. IAM Policy Autopilot, available as a Kiro Power with one-click installation directly from the Kiro IDE, can analyze your application’s usage and generate necessary permissions based on the SDK calls it discovers. IAM Policy Autopilot also integrates as an MCP server with Kiro, Amazon Q Developer, and other MCP-compatible coding assistants, making it a natural part of your existing workflow rather than a separate tool.

    "Review this SCP JSON for syntax errors, overly broad deny statements, and missing condition keys. Flag any statements that could unintentionally block legitimate operations."

    The IAM Policy Simulator then adds another layer of validation on top of the AI-assisted linting, so you can test policy behavior, verify condition keys are correctly applied, and confirm that no legitimate operations are unintentionally blocked. IAM Policy Autopilot complements existing IAM tools such as IAM Access Analyzer by providing functional policies as a starting point, which you can then validate using IAM Access Analyzer policy validation or refine over time with unused access analysis. Together, these tools form a layered validation approach where each one strengthens the output of the previous step.

    Step 3: Test in a sandbox environment:

    Create a test organizational unit (OU) with non-production accounts and apply the SCP to the test OU. Attempt operations that should be blocked and confirm that no legitimate operations are unintentionally blocked. Use Kiro to pre-validate your infrastructure code against the proposed SCP before sandbox testing:

    "Analyze my current infrastructure against this proposed SCP and identify resources that would be non-compliant"

    This scan covers your infrastructure code files. For live account scanning across your organization, use the following AWS services:

    • AWS Config with the Config Aggregator and Conformance Packs for continuous compliance monitoring across your organization.
    • IAM Access Analyzer for automated reasoning-based analysis of external access, internal access, and unused permissions.
    • Account Assessment for AWS Organizations for bulk scanning of identity-based, resource-based, and service control policies across all accounts.
    • Security Hub for centralized aggregation of compliance findings and security scores across your entire organization.

    Step 4: Security architect review:

    Engage your security architects to identify potential risks and verify the policy aligns with your security framework. Check for conflicts with existing SCPs by reviewing all SCPs attached to parent OUs and the root in the AWS Organizations console. Use the IAM Policy Simulator to test interactions between policies and verify that emergency access procedures ( SEC03-BP03 Establish emergency access process – Security Pillar and SEC10-BP05 Pre-provision access – Security Pillar) remain functional before any production rollout.

    Step 5: Staged rollout:

    Deploy to development accounts first and monitor for policy violations and operational issues. Gradually expand to additional environments and maintain documented rollback procedures throughout the process.

    Important: It’s strongly recommended not to deploy AI-generated SCPs directly to production without thorough expert review and staged testing. A misconfigured SCP can cause organization-wide service disruptions affecting every account in your organization.

    Real-world impact:

    SCP drafting that previously required security architects to write and iterate on complex JSON policy documents manually, often spanning multiple review cycles over several days, can be condensed when AI handles the initial drafting and linting. Your architects can then focus their time on policy design, edge case analysis, and organizational impact assessment rather than JSON syntax and structure.

    Responsible implementation framework

    Adopting AI-assisted security workflows is most effective when introduced gradually, with clear validation gates at each stage. The following two-phase approach gives your team time to build confidence, measure results, and establish the internal practices needed before expanding to production environments.

    • Phase 1: Development and testing (weeks 1–4): Start by testing AI-generated security controls in isolated development accounts. Validate functionality, identify edge cases, and deploy to a dedicated testing environment with thorough security validation. Use IAM Access Analyzer, AWS Config, and Security Hub to verify that generated controls behave as expected. This phase is also the right time to build internal expertise across both your security team and your development teams, so that knowledge of what works and what requires human review is shared broadly from the start.
    • Phase 2: Staging and production (week 5 and later): Apply the validated controls to a staging environment that mirrors production. Conduct penetration testing where appropriate and validate that monitoring and alerting function correctly before expanding further. Gradually roll out to production accounts with continuous monitoring in place. Maintain rollback procedures throughout and establish feedback loops so that lessons learned in production flow back into your steering files, rules documents, and validation processes over time.

    Key takeaways

    What distinguishes the approach in this post from general guidance on AI coding assistants is the specificity of the security integration. There’s no shortage of content about how AI assistants accelerate development. What this post focuses on is how to configure both Kiro and Amazon Q Developer to perform security-specific tasks: triaging findings from Security Hub, remediating infrastructure code vulnerabilities against your organization’s defined standards, conducting Well-Architected security reviews, drafting and validating SCPs, and generating secure-by-default infrastructure through persistent context that reflects your environment rather than generic defaults.

    Kiro is an agentic IDE that helps you go from prototype to production with spec-driven development, and its steering files give the agent persistent awareness of your security standards across every session. Amazon Q Developer complements this by providing deep integration into your existing AWS environment and IDE workflows. Together, these tools extend your security team’s reach into every stage of the development lifecycle, scale security expertise into development teams, and reduce the gap between when vulnerabilities are introduced and when they are caught. As the AWS Well-Architected Framework Security Pillar establishes, embedding security early and consistently across the development process is foundational to a strong security posture.

    These five techniques aren’t about replacing your security controls. They’re about making security a natural part of how your teams build on AWS, regardless of whether they’re security specialists or application developers. In addition to the five techniques covered in this post, the following AWS capabilities complement this approach and are worth exploring for a more complete picture:

    • Amazon Inspector is a vulnerability management service that continually scans AWS workloads for software vulnerabilities, code vulnerabilities, and unintended network exposure. It automatically discovers and scans Amazon EC2 instances, container images in Amazon ECR, AWS Lambda functions, and first-party code repositories. Amazon Inspector integrates directly into CI/CD pipelines through plugins for Jenkins, TeamCity, GitHub Actions, and Amazon CodeCatalyst, which teams can use to catch vulnerabilities before deployment. Its code security capabilities include Static Application Security Testing (SAST), Software Composition Analysis (SCA), and infrastructure as code (IaC) scanning, with native integration to GitHub and GitLab. All findings are surfaced directly in Security Hub for centralized visibility and response across your organization.
    • Amazon Q Developer security scanning provides real-time security issue detection in the IDE, including SAST scanning for security vulnerabilities, secrets detection, IaC security evaluation, and software composition analysis for third-party dependencies. These capabilities are available across JetBrains, Visual Studio Code, and Visual Studio.
    • Kiro Powers are curated and pre-packaged MCP servers, steering files, and hooks validated by Kiro partners to accelerate specialized development and deployment use cases. Security-relevant Kiro Powers include the IAM Policy Autopilot Kiro Power for baseline IAM policy generation and the real-time coding security validation MCP server pattern for Kiro.
    • AWS Security Agent is a frontier AI agent that proactively secures your applications throughout the development lifecycle. Security teams define organizational security requirements once in the AWS Security Agent console, such as approved encryption libraries, authentication frameworks, and logging standards, and AWS Security Agent then automatically validates these requirements throughout development by evaluating architectural documents and code against your defined standards. It provides three core capabilities: design security review for architecture documents, code security review that automatically analyzes pull requests against your defined standards across connected repositories, and on-demand penetration testing that discovers, validates, and reports vulnerabilities through sophisticated multi-step attack scenarios customized for each application. When vulnerabilities are found, AWS Security Agent creates pull requests with ready-to-implement fixes directly in your code repository. Customers report that AWS Security Agent compresses penetration testing timelines from weeks to hours, transforming penetration testing from a periodic bottleneck into an on-demand capability that reduces risk exposure and scales security reviews to match development velocity.
    • AWS Security Hub automated response and remediation provides pre-built playbooks for common findings using AWS Systems Manager Automation, enabling your team to act on findings faster and more consistently.

    Getting started

    If you’re new to AI-assisted security workflows, the following week-by-week approach gives your team a practical path forward without overextending before the foundation is in place.

    • Weeks 1 and 2: Set up your persistent context files with your top 10 security policies as described in the foundational setup section above. Configure MCP servers in Kiro for Security Hub and CloudTrail access and verify that credentials are correctly configured for your target accounts.
    • Weeks 3 and 4: Run your first AI-assisted security review on a non-production infrastructure template. Compare the findings against your last manual review to establish a baseline for measuring impact over time.
    • Weeks 5 and 6: pilot AI-assisted SCP drafting for one new preventive control. Run the full validation workflow including AI-assisted linting, IAM Policy Autopilot, and the IAM Policy Simulator before any production application.
    • From that point forward: Measure the metrics outlined in the foundational setup section, update your steering files and rules documents as your standards evolve, and share findings across your security team, development teams, and platform engineering teams. The knowledge of what works and what requires human judgment is valuable to everyone who touches infrastructure in your organization.

    Conclusion

    Kiro and Amazon Q Developer give security teams practical tools to accelerate threat response and maintain consistent security coverage by handling the tasks that consume the most time with the least strategic value: scanning for known misconfigurations, drafting policy JSON, researching CVEs, and generating secure infrastructure. These AI assistants are most effective when paired with security engineers, as they accelerate assessments and code generation while human review, policy design, and risk judgment remain essential throughout.

    By implementing the five techniques outlined in this post, starting with embedding security best practices through persistent context and then applying that foundation to Security Hub finding triage, infrastructure code remediation, in-depth Well-Architected security reviews, and SCP development, your team can strengthen your AWS security posture while maintaining the standards your organization requires.

    AWS services such as Security Hub, IAM Access Analyzer, AWS Config, and CloudTrail provide the foundation for these AI-assisted workflows, enabling centralized visibility and automated validation of security controls across your environment. Emergency access procedures should be established and validated before deploying any preventive controls such as SCPs, following the break-glass guidance in the AWS Well-Architected Security Pillar and the AWS Prescriptive Guidance for break-glass access.

    Start small with non-production environments, establish clear validation processes, measure results, and gradually expand your use of AI assistants as your team builds expertise and confidence. The result is faster threat response, more consistent security coverage, and security engineers focused on complex decisions rather than repetitive tasks.

    Additional resources

    If you have feedback about this post, submit comments in the Comments section below


    Roger Nem

    Roger Nem

    Roger is an Enterprise Technical Account Manager (TAM) supporting Healthcare & Life Science customers at Amazon Web Services (AWS). As a Security Technical Field community specialist, he helps enterprise customers design secure cloud architectures aligned with industry best practices. Beyond his professional pursuits, Roger finds joy in quality time with family and friends, nurturing his passion for music, and exploring new destinations through travel.

    Access control with IAM Identity Center session tags

    Post Syndicated from Rashmi Iyer original https://aws.amazon.com/blogs/security/access-control-with-iam-identity-center-session-tags/

    As organizations expand their Amazon Web Services (AWS) footprint, managing secure, scalable, and cost-efficient access across multiple accounts becomes increasingly important. AWS IAM Identity Center offers a centralized, unified solution for managing workforce access to AWS accounts. It simplifies authentication, enhances security, and provides a seamless user sign-in experience to AWS services across diverse environments.

    By combining IAM Identity Center permission sets with session tags, organizations can unlock powerful capabilities for fine-grained access control and resource optimization. You can use session tags to pass dynamic attributes from your external identity provider into AWS, enabling more context-aware permissions and better cost visibility. This integration makes it possible to use advanced AWS features such as AWS Glue usage profiles and AWS Systems Manager Session Manager run as to enforce fine-grained access control, so that administrators can dynamically map permissions and runtime configurations based on user attributes passed during federated access.

    In this post, I demonstrate how session tags derived from directory group attributes in Microsoft Entra ID can deliver functionality equivalent to AWS Identity and Access Management (IAM) role tags. Using role tags, you can implement attribute-based access control (ABAC) using IAM Identity Center, while maintaining centralized and efficient access management. To demonstrate this, you can configure an AWS Glue usage profile, as described in Introducing AWS Glue usage profiles for flexible cost control, where session tags can be passed through Identity Center and an external identity provider like Microsoft Entra ID. This approach is extensible to other AWS services such as AWS Systems Manager Session Manager (run as) and can also be used with other identity providers.

    User authentication and IAM Identity Center Federation flow

    The following figure shows the architecture and workflow of the solution.

    Figure 1 – User authentication and federation flow between Microsoft Entra and AWS

    Figure 1 – User authentication and federation flow between Microsoft Entra and AWS

    The user authentication and federation flow includes the following steps:

    1. User accesses application using a browser.
    2. The enterprise application (configured in Azure) initiates authentication.
    3. Microsoft Entra ID handles sign-in.
    4. Users and groups are managed in Entra ID.
    5. A SAML trust is established between Entra ID and IAM Identity Center.
    6. SCIM provisioning syncs users and groups from Entra ID to AWS.
    7. Synced users and groups appear in Identity Center.
    8. Session tags are passed during SAML authentication.
      • Entra ID can send user attributes (department, role, cost center, project ID, and so on) as SAML attributes.
      • Identity Center consumes these as session tags, which are used for fine-grained access control and attribute-based access control inside AWS.
    9. Admins define permission sets for users and groups in Identity Center.
    10. Users get federated access to AWS using their Entra ID credentials.
    11. Users sign in through AWS Management Console or AWS Command Line Interface (AWS CLI) using those permissions.
    12. Access is granted to specific AWS accounts under AWS Organizations.

    Prerequisites

    To follow the steps in this post, you need the following prerequisites:

    1. An organization instance of IAM Identity Center enabled.
    2. A Microsoft Entra ID tenant. For more information, see Quickstart: Create a new tenant in Microsoft Entra ID.
    3. Access to an external identity provider such as Microsoft Entra ID to federate users into AWS. You can enable federated access between Microsoft Entra ID and IAM Identity Center by completing the steps in Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center. They include configuring SAML and SCIM integration between the two systems, testing the SAML connection to help ensure authentication is functioning correctly, and enabling SCIM synchronization to automate user and group provisioning.

    Solution implementation

    With the prerequisites in place, you’re ready to configure access control through IAM Identity center tags by using the following steps.

    1. Create an AWS Glue usage profile as described in Introducing AWS Glue usage profiles for flexible cost control in Create an AWS Glue usage profile. For the purposes of this post, create a profile named developer.
      1. On the AWS Management Console for AWS Glue, choose Cost management in the navigation pane.
      2. Choose Create usage profile.
      3. For Usage profile name, enter developer.
      4. Under Customize configurations for jobs, for Number of workers, for Default, enter 20.
      5. For Default worker type, select G.1X.
      6. For Allowed worker types, select G.1X, G.2X, G.4X, and G.8X.
      7. For Customize configurations for sessions, configure the same values.
      8. Choose Create usage profile.
      Figure 2 – Glue usage profile creation on the console

      Figure 2 – Glue usage profile creation on the console

    2. Create a custom permission set instead of using predefined ones. Attach the following AWS Managed Policies to the custom permission set:
      • AWSGlueConsoleFullAccess
      • IAMReadOnlyAccess

      Note: For fine-grained access control, you can create custom permission sets by combining AWS managed, customer managed, and inline policies in IAM. In this post, you use AWS managed policies with intentionally broad permissions for simplicity. In production, always follow the principles of least privilege and scope permissions appropriately.

      By default, when you create a permission set, the permission set isn’t provisioned (used in any AWS accounts). To provision a permission set in an AWS account, you must assign IAM Identity Center access to users or groups in the account and then apply the permission set to those users and groups. For more information, see Assign user or group access to AWS accounts.

    3. Configure user attributes in Microsoft Entra ID for access control in IAM Identity Center as described in Step 5 of Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center to set up ABAC. Add claim conditions for attribute mapping based on Entra ID group membership. Assign the developer value for users in a corresponding group. This enables logic such as Users in this group receive this profile or All users receive this profile. When using an AWS Glue profile and when making API calls to create AWS Glue resources, admins need to tag the user or role with glue:UsageProfile as the key and the profile name as the value.
    4. Next, sign in to the enterprise application that you created in the previous step, which has SCIM and SAML connections set up to IAM Identity Center:
      1. Sign in to Azure.
      2. Choose Enterprise applications.
      3. Select the application that you created
        Figure 3 – An enterprise application created in Microsoft Entra ID

        Figure 3 – An enterprise application created in Microsoft Entra ID

    5. When you’re signed in to your application, select Manage and then Single sign-on in the navigation pane, then select Attributes & Claims.
      Figure 4 – Attributes & Claims section in Microsoft Entra ID

      Figure 4 – Attributes & Claims section in Microsoft Entra ID

    6. Configure the key value pair that will used as session tags by selecting Add new claim.
      Figure 5 – Configuring attributes by adding a new claim

      Figure 5 – Configuring attributes by adding a new claim

    7. For Name, enter AccessControl:<AttributeName>. Replace <AttributeName> with the name of the attribute you are expecting in IAM Identity Center. For this example, use AccessControl:glue:UsageProfile.
    8. In Claim conditions set the following:
      • User type, select Members
      • Source, select Attribute.
      • Value, enter developer (without quotation marks).
      Figure 6 – Attribute claim addition in Microsoft Entra using group membership

      Figure 6 – Attribute claim addition in Microsoft Entra using group membership

    It’s important to note that the tags are being assigned based on group membership in Microsoft Entra ID. This approach lets you manage access and configuration dynamically without needing to set tags individually for each user. By assigning the tag to a Microsoft Entra ID group, anyone signing in to IAM Identity Center and who is in that group will automatically have the tag value applied to their session.

    Test the solution

    Now that the required configuration is complete, test the setup using the developer usage profile created as part of the Solution implementation section. Sign in as your user through Microsoft Entra ID using https://myapps.microsoft.com/ and verify the job creation using the following steps mentioned.

    To verify successful job creation:

    1. Open the AWS Glue console using the developer usage profile.
    2. In the navigation pane, choose ETL jobs.
    3. Select Script editor, then choose Create script.
    4. Create a new job using the values you want to validate.

    The green banner at the top of the screen should say Successfully updated job.

    Figure 7 – Successful AWS Glue job creation with configured parameters for the <em>developer</em> usage profile” width=”678″ height=”864″ class=”size-full wp-image-41907″></p>
<p id=Figure 7 – Successful AWS Glue job creation with configured parameters for the developer usage profile

    Validation using AWS CloudTrail

    Examine the AssumeRoleWithSAML event using AWS Cloudtrail. Use the following steps to verify the sequence of events.

    1. Navigate to the CloudTrail console.
    2. Select Event history.
    3. In the Lookup attributes dropdown, select Event name.
    4. Set the event name to AssumeRoleWithSAML.
    5. Open a relevant event and inspect the requestParameters section.
    6. Confirm that the expected session tags appear under PrincipalTags.
    Figure 8 – ABAC tags passed during the role assumption

    Figure 8 – ABAC tags passed during the role assumption

    Using session tags for other use cases

    The concepts discussed in this post can be extended to configure AWS Systems Manager Session Manager Run As support for federated users using session tags. By default, Session Manager launches sessions using a system-generated ssm-user account. For Linux instances, you can optionally configure sessions to run as a specific OS-level user through Session Manager preferences. You can configure your identity provider to pass the user attribute (AccessControl: SSMSessionRunAs and name of an OS user account for the key value during federation and the session will be tagged using the attribute value.

    Clean up

    To avoid incurring future charges, delete any resources created during this walkthrough if they’re no longer needed:

    1. Remove the IAM Identity Center instance and clean up the associated enterprise application in Microsoft Entra.
    2. Delete the AWS Glue usage profile.
    3. Remove any other AWS resources you provisioned for testing the solution.

    Conclusion

    In this post, you learned how to federate access to AWS using AWS IAM Identity Center and SAML 2.0 identity providers like Microsoft Entra ID, enabling a secure, scalable, and centralized approach to managing user access across multiple AWS accounts. By using permission sets, reserved IAM roles, and session tags, organizations can implement fine-grained ABAC without the complexity of managing individual IAM users or static roles.

    As cloud environments become more complex, adopting modern identity federation and ABAC through IAM Identity Center helps security teams maintain control while providing users with seamless, context-aware access to the resources they need.

    Resources

    If you have feedback about this post, submit comments in the Comments section below.

    Rashmi Iyer

    Rashmi Iyer

    Rashmi is a Senior Solutions Architect at AWS, supporting financial services enterprises in building secure, resilient, and scalable cloud architectures while ensuring compliance with industry best practices. With over 15 years of experience in the private telco cloud, she has designed and architected complex telecom solutions, specializing in the packet core domain, the backbone of mobile data networks.

    Migrate to Apache Flink 2.2 on Amazon Managed Service for Apache Flink

    Post Syndicated from Francisco Morillo original https://aws.amazon.com/blogs/big-data/migrate-to-apache-flink-2-2-on-amazon-managed-service-for-apache-flink/

    Migrating to Apache Flink 2.2 on Amazon Managed Service for Apache Flink gives you access to Java 17 runtime, faster checkpoints and recovery through RocksDB 8.10.0, and SQL-native artificial intelligence and machine learning (AI/ML) inference. If you run Flink 1.x today, you might be dealing with an aging Java 11 runtime that will no longer receive standard support by the end of this year, slower state backend performance, and a fragmented API surface split across DataSet, DataStream, and legacy connector interfaces. Flink 2.2 addresses these gaps in a single major version upgrade.

    Apache Flink is an open source distributed processing engine for stream and batch data, with first-class support for stateful processing and event-time semantics. Amazon Managed Service for Apache Flink removes the operational overhead of running Flink. You provide your application code, and the service provisions, scales, checkpoints, and patches the infrastructure for you.

    In this post, we explain what’s new in Amazon Managed Service for Apache Flink 2.2, provide a guided migration using CLI commands, console instructions, and code examples, and show you how to monitor the upgrade and roll back if needed.

    Before you upgrade: Flink 2.2 removes the DataSet API, drops Java 11 support, and replaces legacy connector interfaces. We recommend reviewing the Upgrading to Flink 2.2: Complete Guide and the State Compatibility Guide for Flink 2.2 Upgrades before upgrading production applications.

    What’s new in Amazon Managed Service for Apache Flink 2.2

    This release spans runtime upgrades, SQL, and Table API capabilities. The following sections break down each area.

    Runtime and performance

    These changes improve application performance and bring your runtime up to current standards.

    • Java 17 runtime – Flink 2.2 requires Java 17. Build your application code with JDK 17 for better garbage collection, a more secure runtime, and modern language features like sealed classes and records. Java 11 is no longer supported.
    • Python 3.12 – Flink 2.2 requires Python 3.9+, with Python 3.12 as the default. Python 3.8 is no longer supported.
    • RocksDB 8.10.0 – Your stateful applications benefit from improved I/O performance with the upgraded state backend, resulting in faster checkpoints and recovery.
    • Dedicated collection serializers – Improved serializers for Map, List, and Set types reduce serialization overhead, which lowers checkpoint sizes for applications that use these data structures frequently.
    • Kryo 5.6 – Kryo upgrades from version 2.24–5.6. This has state compatibility implications covered in the migration section.

    SQL and Table API highlights

    With Flink 2.2, you can:

    For details on these features, see the Apache Flink 2.2 release documentation.

    Migrating from Flink 1.x to 2.2

    In-place version upgrades

    You can upgrade a running Flink 1.x application to 2.2 using the UpdateApplication API, the AWS Management Console, AWS CloudFormation, the AWS SDK, and Terraform Modules. The upgrade preserves your application configuration, logs, metrics, tags, and, if your state and binaries are compatible.

    Auto-rollback

    With auto-rollback turned on, binary incompatibilities detected during job startup trigger an automatic revert to the previous Flink version within minutes, with no manual intervention required. For state incompatibilities that surface as restart loops after a successful upgrade, invoke the Rollback API to return to your previous version and state.

    Unsupported open source features

    The following Flink 2.2 features aren’t currently supported in Amazon Managed Service for Apache Flink because they’re still considered experimental: Materialized Tables, ForSt State Backend (disaggregated state storage), Java 21, and custom metric reporters/telemetry configurations. We continue to evaluate these features as they mature in the Apache Flink project and will share updates on availability. You can have a closer look to which features are supported in Apache Flink 2.2 features supported

    Now that you know what’s changed, the next section walks through the migration process.

    Prerequisites

    Before starting the migration, confirm that you have the following in place:

    • An existing Apache Flink 1.x application running on Amazon Managed Service for Apache Flink.
    • JDK 17 installed in your local build environment.
    • The AWS Command Line Interface (AWS CLI) installed and configured with permissions to call the kinesisanalyticsv2 APIs (UpdateApplication, CreateApplicationSnapshot, DescribeApplication, RollbackApplication).
    • An Amazon Simple Storage Service (Amazon S3) bucket to upload your updated application JAR.

    We recommend testing each phase on a non-production replica of your application before applying the same steps to production.

    Step 1: Update your application code

    Start by updating your Flink dependencies to version 2.2.0 and replacing deprecated APIs. The following sections show the most common changes.

    Update your pom.xml:

    <properties>
        <flink.version>2.2.0</flink.version>
        <java.version>17</java.version>
    </properties>

    Replace legacy Kinesis connectors:

    Flink 2.2 removes the FlinkKinesisConsumer and FlinkKinesisProducer classes. The following example shows how to migrate to the FLIP-27 based KinesisStreamsSource.Before (Flink 1.x):

    FlinkKinesisConsumer<String> consumer = new FlinkKinesisConsumer<>(
        "my-stream",
        new SimpleStringSchema(),
        consumerConfig);
    env.addSource(consumer);

    After (Flink 2.2):

    KinesisStreamsSource<String> source = KinesisStreamsSource.<String>builder()
        .setStreamArn("arn:aws:kinesis:us-east-1:123456789012:stream/my-stream")
        .setDeserializationSchema(new SimpleStringSchema())
        .build();
    env.fromSource(source, WatermarkStrategy.noWatermarks(), "Kinesis Source");

    Update connector dependencies:

    The following AWS connectors have Flink 2.x-compatible releases:

    Connector Flink 2.x Artifact Version
    Apache Kafka flink-connector-kafka 4.0.0-2.0
    Amazon Kinesis Data Streams flink-connector-aws-kinesis-streams 6.0.0-2.0
    Amazon Data Firehose flink-connector-aws-kinesis-firehose 6.0.0-2.0
    Amazon DynamoDB flink-connector-dynamodb 6.0.0-2.0
    Amazon Simple Queue Service (Amazon SQS) flink-connector-sqs 6.0.0-2.0

    During writing, the JDBC, OpenSearch, and Prometheus connectors don’t yet have Flink 2.x-compatible releases. For the latest versions, see the Amazon Managed Service for Apache Flink connector documentation.

    Beyond connector updates, make the following code changes:

    • Replace DataSet API usage with the DataStream API or Table API/SQL.
    • Replace Scala API usage with the Java API.
    • Verify that your build targets JDK 17.

    Build your updated application JAR and upload it to Amazon S3 with a different file name than your current JAR (for example, my-app-flink-2.2.jar).

    Step 2: Check state compatibility

    Before upgrading, assess whether your application state is compatible with Flink 2.2. The Kryo upgrade from version 2.24 to 5.6 changes the binary format of serialized state. Applications using POJOs with Java collections (HashMap, ArrayList, HashSet) are the most common source of incompatibility.

    Quick compatibility check:

    Serialization type Compatible?
    Avro (SpecificRecord, GenericRecord) ✅ Yes
    Protobuf ✅ Yes
    POJOs without collections ✅ Yes
    Custom TypeSerializers (no Kryo delegation) ✅ Yes
    POJOs with Java collections ❌ No
    Scala case classes ❌ No
    Types using Kryo fallback ❌ No

    Check your logs for Kryo fallback:

    Search your application logs for this pattern, which indicates a type is falling back to Kryo serialization:Class class <className> cannot be used as a POJO type

    Step 3: Turn on auto-rollback and automatic snapshots

    Turn on auto-rollback so the service automatically reverts to the previous version if the upgrade fails. Also, verify that automatic snapshots are turned on. The service takes a snapshot before the upgrade that serves as your rollback point.

    Check current settings:

    aws kinesisanalyticsv2 describe-application \
        --application-name MyApplication \
        --query 'ApplicationDetail.ApplicationConfigurationDescription.{
            AutoRollback: ApplicationSystemRollbackConfigurationDescription.RollbackEnabled,
            AutoSnapshots: ApplicationSnapshotConfigurationDescription.SnapshotsEnabled
        }'

    Turn on both if they’re not already active:

    aws kinesisanalyticsv2 update-application \
        --application-name MyApplication \
        --current-application-version-id <version-id> \
        --application-configuration-update '{
            "ApplicationSystemRollbackConfigurationUpdate": {
                "RollbackEnabledUpdate": true
            },
            "ApplicationSnapshotConfigurationUpdate": {
                "SnapshotsEnabledUpdate": true
            }
        }'

    Step 4: Take a manual snapshot (recommended)

    Although the upgrade process takes an automatic snapshot, taking a manual snapshot gives you a named restore point that you can quickly identify.

    aws kinesisanalyticsv2 create-application-snapshot \
        --application-name MyApplication \
        --snapshot-name pre-flink-2.2-upgrade

    Verify that the snapshot is ready before proceeding:

    aws kinesisanalyticsv2 describe-application-snapshot \
        --application-name MyApplication \
        --snapshot-name pre-flink-2.2-upgrade

    Wait until SnapshotStatus is READY.

    Step 5: Run the upgrade

    Run the upgrade while the application is in RUNNING or READY (stopped) state. The following example upgrades a running application and points to the new JAR.

    AWS CLI:

    aws kinesisanalyticsv2 update-application \
        --application-name MyApplication \
        --current-application-version-id <version-id> \
        --runtime-environment-update FLINK-2_2 \
        --application-configuration-update '{
            "ApplicationCodeConfigurationUpdate": {
                "CodeContentUpdate": {
                    "S3ContentLocationUpdate": {
                        "FileKeyUpdate": "my-app-flink-2.2.jar"
                    }
                }
            }
        }'

    AWS Management Console:

    To upgrade from the console, follow these steps:

    1. Navigate to your application in the Amazon Managed Service for Apache Flink console.
    2. Choose Configure.
    3. Select the Flink 2.2 runtime.
    4. Point to your new application JAR on Amazon S3.
    5. Select the snapshot to restore from (use Latest to start from the most recent snapshot).
    6. Choose Update.

    AWS CloudFormation:

    Update the RuntimeEnvironment field in your template. AWS CloudFormation now performs an in-place update instead of deleting and recreating the application.

    Terraform:

    If you manage your Flink application with Terraform, you can perform the same in-place upgrade by updating the runtime_environment and code reference in your aws_kinesisanalyticsv2_application resource. Note: Terraform support for FLINK-2_2 requires AWS provider version 6.40.0 or later (released April 8, 2026). Earlier provider versions don’t recognize this runtime value. First, update your provider version constraint:

    terraform {
      required_providers {
        aws = {
          source  = "hashicorp/aws"
          version = ">= 6.40.0"
        }
      }
    }

    Then run terraform init -upgrade to pull the new provider.Next, update your application resource. Change runtime_environment from “FLINK-1_20” to “FLINK-2_2” and point to your new JAR:

    resource "aws_kinesisanalyticsv2_application" "my_app" {
      name                   = "MyApplication"
      runtime_environment    = "FLINK-2_2"
      service_execution_role = aws_iam_role.flink.arn
      application_configuration {
        application_code_configuration {
          code_content_type = "ZIPFILE"
          code_content {
            s3_content_location {
              bucket_arn = aws_s3_bucket.app_code.arn
              file_key   = "my-app-flink-2.2.jar"
            }
          }
        }
        application_snapshot_configuration {
          snapshots_enabled = true
        }
        flink_application_configuration {
          checkpoint_configuration {
            configuration_type = "DEFAULT"
          }
          monitoring_configuration {
            configuration_type = "CUSTOM"
            log_level          = "INFO"
            metrics_level      = "APPLICATION"
          }
          parallelism_configuration {
            auto_scaling_enabled = true
            configuration_type   = "CUSTOM"
            parallelism          = 4
            parallelism_per_kpu  = 1
          }
        }
      }
    }

    Run the upgrade:

    terraform plan    # Review the in-place update
    terraform apply   # Apply the runtime change

    Terraform will perform an in-place update of the application, changing the runtime version and code location. The application will restart with the new Flink 2.2 runtime. To roll back with Terraform, revert runtime_environment to “FLINK-1_20”, point file_key back to your original JAR, and run terraform apply again. Note that you cannot restore a Flink 2.2 snapshot on Flink 1.x, so the rollback will start from the last Flink 1.x snapshot.

    Important Terraform considerations:

    • Auto-rollback and the RollbackApplication API aren’t directly exposed as Terraform resource attributes. If you need auto-rollback during the upgrade, enable it using the AWS CLI (Step 3) before running terraform apply, or use a provisioner/null_resource to call the CLI.
    • Always take a manual snapshot (Step 4) before running terraform apply for the upgrade. Terraform doesn’t automatically snapshot before updating the runtime.

    Step 6: Monitor the upgrade

    After initiating the upgrade, monitor the application to verify that it completes successfully.

    Check application status:

    The application should transition through RUNNING → UPDATING → RUNNING. Confirm the runtime version changed to 2.2:

    aws kinesisanalyticsv2 describe-application \
        --application-name MyApplication \
        --query 'ApplicationDetail.RuntimeEnvironment'

    What to watch for:

    Scenario What happens Action
    Binary incompatibility Upgrade operation fails. Auto-rollback reverts to the previous version automatically. Check operation logs for the exception, fix your code, and retry.
    State incompatibility Upgrade appears to succeed but the application enters restart loops. Monitor numRestarts metric. If restarts are continuous, invoke the Rollback API manually. Review the [State Compatibility Guide].
    Successful upgrade numRestarts is zero, uptime is increasing, checkpoints are completing. Proceed to validation.

    Key CloudWatch metrics to monitor:

    1. numRestarts: should be zero after upgrade
    2. lastCheckpointDuration: should be similar to pre-upgrade values
    3. numberOfFailedCheckpoints: should remain at zero
    4. uptime: should be steadily increasing

    Step 7: Validate application behavior

    After the application is running on Flink 2.2:

    • Confirm that data is being read from sources and written to sinks.
    • Compare the output with your pre-upgrade baseline.
    • Monitor latency, throughput, checkpoint duration, and resource utilization.
    • Run for at least 24 hours to confirm stable behavior: no memory leaks, no unexpected restarts, consistent checkpoint sizes.

    Step 8: Rollback (if needed)

    If the application is running but is unhealthy after the upgrade, invoke the Rollback API:

    AWS CLI:

    aws kinesisanalyticsv2 rollback-application \
        --application-name MyApplication \
        --current-application-version-id <version-id>

    AWS Management Console:

    • Navigate to your application.
    • Choose Actions, Roll back.
    • Confirm the rollback.

    During rollback, the application stops, reverts to the previous Flink version and application code, and restarts from the snapshot taken before the upgrade.

    Important: You can’t restore a Flink 2.2 snapshot on Flink 1.x. Rollback uses the snapshot taken before the upgrade. This is why Steps 3 and 4 are critical.

    Next steps

    Your path depends on where you are today:

    1. If you’re new to Apache Flink: Start with the guide to choosing the right API and language, the Amazon Managed Service for Apache Flink getting started guide, and the Amazon Managed Service for Apache Flink workshop.
    2. If you’re running Flink 1.x in production: Follow the migration steps in this post on a non-production replica first, then apply to production. For the complete reference, see the Upgrading to Flink 2.2: Complete Guide and the State Compatibility Guide for Flink 2.2 Upgrades.
    3. If you’re evaluating Flink 2.2 features: Launch a new application on the Flink 2.2 runtime to explore SQL/ML capabilities, the VARIANT data type, and the new join operators. See the Amazon Managed Service for Apache Flink sample applications on GitHub for reference architectures.
    4. If you need help with your migration: Use the Kiro Power and Agent Skill for Amazon Managed Service for Apache Flink to identify compatibility issues in your existing codebase and receive guidance on refactoring steps. You can also open a case through AWS Support, post a question on AWS re:Post for Amazon Managed Service for Apache Flink, or reach out through the Apache Flink community.

    For the Apache Flink 2.2 documentation, see nightlies.apache.org/flink/flink-docs-release-2.2. For Amazon Managed Service for Apache Flink documentation, see the Developer Guide. For pricing, see the pricing page.
    Conclusion

    With Apache Flink 2.2 on Amazon Managed Service for Apache Flink, you get a modern Java 17 runtime, SQL-native AI/ML inference, improved state management performance, and a streamlined API surface. In-place upgrades with state preservation and auto-rollback make the migration straightforward. Test on a replica, follow the steps in this post, and start building on Flink 2.2.


    About the authors

    Francisco Morillo

    Francisco Morillo is a Sr. Streaming Specialist Solutions Architect at AWS, helping customers design and operate real-time data processing applications using Amazon Managed Service for Apache Flink and Amazon Managed Streaming for Apache Kafka.

    Mayank Juneja

    Mayank Juneja is a Senior Product Manager at AWS, leading Amazon Managed Service for Apache Flink. He lives at the intersection of real-time data streaming and AI, previously driving Flink SQL and AI inference products at Confluent.

    Can I do that with policy? Understanding the AWS Service Authorization Reference

    Post Syndicated from Anshu Bathla original https://aws.amazon.com/blogs/security/can-i-do-that-with-policy-understanding-the-aws-service-authorization-reference/

    Understanding what AWS Identity and Access Management (IAM) policies can control helps you build better security controls and avoid spending time on approaches that won’t work. You’ve likely encountered questions like:

    • Can I use AWS Organizations service control policies (SCPs) to prevent the creation of security groups that allow traffic from 0.0.0.0/0?
    • Can I block uploads unless objects are encrypted?
    • Can I prevent functions with more than 512 MB of memory allocated?

    Some of these are possible with IAM policies. Others are not. The difference is determined by a fundamental principle of AWS authorization: Policies make decisions based on information available in the authorization context at the time of the API call.

    In this blog post, you learn how to use the AWS Service Authorization Reference to determine what’s achievable with IAM policies, recognize scenarios that need alternative solutions, and build more effective security controls in your AWS environment.

    Understanding AWS authorization context

    When you make an AWS API request through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDK, the specific AWS service (such as Amazon S3 or Amazon EC2) receiving the request assembles a request context containing information about that request. This context is used for policy evaluation decisions. Request context is structured using the Principal, Action, Resource, Condition (PARC) model, which has four key components.

    • Principal: Identifies the requester and their attributes (tags, session context)
    • Action: Specifies the AWS API operation being requested (for example, s3:PutObject, ec2:RunInstances)
    • Resource: Defines the target AWS resource using Amazon Resource Names (ARNs)
    • Condition: Provides additional context available at request time, such as IP address, time, encryption parameters, MFA status, and service-specific attributes

    The following example shows the typical request context for an Amazon S3 object upload:

    • Principal: AIDA123456789EXAMPLE
    • Action: s3:PutObject
    • Resource: arn:aws:s3:::my-bucket/documents/samplereport.pdf
    • Condition:
      • aws:PrincipalTag/Department=Finance
      • aws:RequestedRegion=us-east-1
      • aws:SourceIp=x.x.x.x
      • aws:MultiFactorAuthPresent=true
      • s3:x-amz-server-side-encryption=AES256
      • s3:x-amz-storage-class=STANDARD_IA

    IAM policies can evaluate request metadata like encryption method and storage class being specified. However, it cannot evaluate the actual file contents, object size, or specific data patterns. Policy evaluation occurs at the time of the request, using the information present in the authorization context.

    An essential resource: The Service Authorization Reference

    The Service Authorization Reference is the authoritative documentation for understanding what policies can control. For every AWS service, it documents:

    • Actions: Every controllable operation
    • Resources: Resource types that can be targeted
    • Condition keys: The exact context information available for policy decisions

    Condition keys are broadly divided into two categories. Global condition keys, which can be used across AWS services, and service-specific condition keys, which are defined for use with an individual AWS service. Use the Service Authorization Reference to find the global-condition keys or service-specific condition keys for each AWS service.

    How to use the Service Authorization Reference

    Follow these steps to determine if your requirement can be controlled with IAM policies:

    1. Navigate to your service: Go to the page for the specific AWS service you’re working with, such as Actions, resources, and condition keys for Amazon S3.
    2. Find the action you want: Find the API operation you want to control. Be precise, different actions have different available condition keys.
    3. Examine available condition keys: The Condition keys column shows what context information AWS makes available for that action.
    4. Make your feasibility determination: If the information you need isn’t listed as a condition key, you will not be able to control it with IAM policies alone.

    Let’s take an example from the Amazon Elastic Compute Cloud (Amazon EC2) ec2:RunInstances action to see what you can and can’t control. In the Service Authorization Reference under the Amazon EC2 section, examine the RunInstances action and check the Resource types column. The RunInstances action affects multiple resource types, each with its own set of condition keys.

    For the instance* resource type:

    • ec2:InstanceType: Can restrict instance types
    • ec2:EbsOptimized: Can require EBS optimization
    • aws:RequestTag/: Can enforce tagging requirements

    For the network-interface* resource type:

    • ec2:Subnet: Can control subnet placement
    • ec2:Vpc: Can limit to specific virtual private clouds (VPCs)
    • ec2:AssociatePublicIpAddress: Can control public IP assignment

    Note: These are a few examples from the many condition keys available for each resource type under the RunInstances action. The Service Authorization Reference lists dozens of condition keys across resource types (instance, network interface, security group, subnet, volume, and so on) that RunInstances affects. Consult the complete reference to see the available options for your specific use case.

    Access the Service Authorization Reference programmatically

    Beyond the human-readable documentation, AWS provides the Service Authorization Reference in machine-readable JSON format to streamline automation of policy management workflows. Use this programmatic access to incorporate authorization metadata into your development and security workflows.
    For detailed information about the JSON structure and field definitions, see the Simplified AWS service information for programmatic access.
    Developers can use tools like the IAM MCP Server for AWS IAM operations. This server provides AI assistants with the ability to manage IAM users, roles, policies, and permissions while following security best practices.

    Using IAM policies to control specific scenarios

    The following examples show how you can use IAM policies to control specific scenarios.

    Example 1: Enforce AES256 server-side encryption on S3 objects

    In the Amazon S3 Service Authorization Reference, under s3:PutObject action, the s3:x-amz-server-side-encryption condition key is available in the authorization context, which can be used to control the server-side encryption of S3 objects with AES-256. Here is the required policy.

    Policy 1: Deny Amazon S3 object upload if the encryption doesn’t use AES-256

    {
    	"Version": "2012-10-17",
    	"Statement": [
    		{
    			"Sid": "DenyUnencryptedObjectUploads",
    			"Effect": "Deny",
    			"Action": "s3:PutObject",
    			"Resource": "arn:aws:s3:::my-bucket/*",
    			"Condition": {
    				"StringNotEquals": {
    					"s3:x-amz-server-side-encryption": "AES256"
    				}
    			}
    		}
    	]
    }

    Policy 1 is a resource-based policy that can be applied on an S3 bucket to restrict object uploads. It denies a PutObject request when the server-side encryption isn’t using the AES-256 encryption algorithm.

    Example 2: Allow different instance types based on the user’s cost center tag.

    When checking the Amazon EC2 Service Authorization Reference for ec2:RunInstances, the ec2:InstanceType condition key, which is resource specific, is available. To restrict instance types based on who is launching them (rather than just what is being launched), you can either combine this with a global condition key or attach different policies to different principals. By using aws:PrincipalTag/tag-key alongside ec2:InstanceType, you can identify the user’s cost center from their IAM identity tags and then apply different instance type restrictions accordingly. This allows a single policy to dynamically enforce different permissions based on the requester’s identity.

    Policy 2: Restricting EC2 instance types by cost center

    {
    	"Version": "2012-10-17",
    	"Statement": [
    		{
    			"Sid": "AllowDevInstanceTypes",
    			"Effect": "Allow",
    			"Action": "ec2:RunInstances",
    			"Resource": "arn:aws:ec2:*:*:instance/*",
    			"Condition": {
    				"StringEquals": {
    					"aws:PrincipalTag/CostCenter": "Development"
    				},
    				"StringLike": {
    					"ec2:InstanceType": "t3.*"
    				}
    			}
    		},
    		{
    			"Sid": "AllowProdInstanceTypes",
    			"Effect": "Allow",
    			"Action": "ec2:RunInstances",
    			"Resource": "arn:aws:ec2:*:*:instance/*",
    			"Condition": {
    				"StringEquals": {
    					"aws:PrincipalTag/CostCenter": "Production"
    				},
    				"StringLike": {
    					"ec2:InstanceType": [
    						"m5.*",
    						"c5.*",
    						"r5.*"
    					]
    				}
    			}
    		}
    	]
    }

    This is an identity-based policy that you can attach to IAM users, groups, or roles to control EC2 instance launches based on cost allocation. In the first statement, aws:PrincipalTag, which is a global condition key (tags attached to the IAM user or role), is used to determine which instance types are allowed. Users tagged with CostCenter=Development can only launch cost-effective T3 instance types (t3.micro, t3.small, t3.medium, and so on)with the service specific key ec2:InstanceType.

    In the second statement, users tagged with CostCenter=Production can launch more powerful instance types from the M5 (general purpose), C5 (compute optimized), and R5 (memory optimized) families. This approach lets organizations enforce cost controls and allocate resources based on workload requirements. Each cost center maintains flexibility for its specific needs.

    Note: Additional resources are required in the IAM policy to successfully launch EC2 instances. For the complete list, see Launch Instances.

    Example 3: Users can only access and update DynamoDB items where the partition key matches their username.

    You have identified that GetItem, PutItem,and UpdateItem actions are required. Corresponding to these actions, you can use the condition key to expose partition key values in the authorization context as described in the Amazon DynamoDB Service Authorization Reference

    Policy 3: DynamoDB fine-grained access control

    {
    	"Version": "2012-10-17",
    	"Statement": [
    		{
    			"Effect": "Allow",
    			"Action": [
    				"dynamodb:GetItem",
    				"dynamodb:PutItem",
    				"dynamodb:UpdateItem"
    			],
    			"Resource": "arn:aws:dynamodb:us-east-1:111122223333:table/UserProfiles",
    			"Condition": {
    				"ForAllValues:StringEquals": {
    					"dynamodb:LeadingKeys": ["${aws:username}"]
    				}
    			}
    		}
    	]
    }

    The policy allows users to perform read and write actions (GetItem, PutItem, and UpdateItem) on the UserProfiles table, but only for items where the partition key value equals their own username (using the ${aws:username} policy variable). For example, if user alice attempts to access an item with partition key bob, the request will be denied.

    Scenarios that need more than policies alone

    Some requirements can’t be met using IAM policies. Here are three common scenarios that aren’t achievable with IAM policies alone.

    Scenario 1: Block users from creating security group rules that allow traffic from 0.0.0.0/0 on TCP port 22

    Upon checking the Amazon EC2 Service Authorization Reference, you will find that the ec2:AuthorizeSecurityGroupIngress action is required in an IAM policy to add an inbound access rules to a security group.

    To verify this in the Service Authorization Reference, navigate to the Amazon EC2 Service Authorization Reference and search for the AuthorizeSecurityGroupIngress action, which is the action that creates security group rules. After you locate this action, review the Condition keys column and look for condition keys related to CIDR blocks, IP ranges, ports, or protocols. Available condition keys for ec2:AuthorizeSecurityGroupIngress include:

    Notice there are no condition keys for CIDR blocks (such as 0.0.0.0/0), port numbers (such as 22), or protocols (such as TCP). The authorization context doesn’t include information about the specific CIDR blocks, ports, or protocols being added to the security group rule, so IAM policies can’t control these attributes.

    Solution
    Take a reactive approach using the AWS Config managed rule INCOMING_SSH_DISABLED to detect overly permissive rules. You can also use a combination of Amazon EventBridge and Lambda to either send a notification to your security team for the non-compliant configuration or to restrict the security group through an automation. For more information, see How to Automatically Revert and Receive Notifications About Changes to Your Amazon VPC Security Groups.

    Scenario 2: Prevent creation of Lambda functions with more than 512 MB of memory allocated

    Following the same verification methodology described in Scenario 1, navigate to the AWS Lambda Service Authorization Reference and examine the CreateFunction action’s condition keys for the function* resource type.

    Available condition keys for lambda:CreateFunction with the function* resource type include:

    • lambda:CodeSigningConfigArn: Filters access by the ARN of the code signing
    • configuration-lambda:Layer: Filters access by the ARN of a version of an AWS Lambda layer
    • lambda:VpcIds: Filters access by the ID of the VPC configured for the Lambda function

    There is no condition key for memory allocation (MemorySize parameter), timeout settings, storage configuration (EphemeralStorage), or runtime selection. Because memory allocation isn’t exposed in the authorization context, IAM policies can’t restrict this parameter.

    Solution

    Key takeaways

    Keep these principles in mind when working with IAM policies:

    • Policies control what’s in the authorization context, not all elements you see in API documentation
    • The Service Authorization Reference is authoritative; if something isn’t listed as a condition key, you can’t control it with policies
    • Different actions have different available contexts even within the same service
    • Alternative approaches exist. AWS Config, EventBridge, and service-specific controls can be used to achieve your goals when policies alone can’t
    • Layered security is essential; combine preventive, detective, and responsive controls to help ensure that your data is secure

    Conclusion

    In this post, you learned how to use the AWS Service Authorization Reference to determine what’s achievable with IAM policies and recognize scenarios that require alternative solutions. By understanding that policies can only make decisions based on information available in the authorization context, you can build more effective security controls and avoid spending time on approaches that won’t work.

    The Service Authorization Reference is your authoritative source for understanding policy capabilities. When you need to implement a control, start there to see if the required condition keys exist. If they don’t, you will need to layer in detective or responsive controls using services like AWS Config, Amazon EventBridge, or AWS Lambda.

    Remember that effective AWS security isn’t about finding one perfect control, it’s about combining preventive, detective, and responsive measures to create defense in depth. IAM policies are powerful tools for prevention and work as part of a comprehensive security strategy.

    Next steps:

    If you have feedback about this post, submit comments in the Comments section below.


    Author

    Anshu Bathla

    Anshu is a Senior Lead Consultant – SRC at AWS, based in Gurugram, India. He works with customers across diverse verticals to help strengthen their security infrastructure and achieve their security goals. Outside of work, Anshu enjoys reading books and gardening at his home garden.

    Author

    Prafful Gupta

    Prafful is an Associate Delivery Consultant at AWS, based in Gurugram, India. Having started his professional journey with Amazon, he specializes in DevOps and Generative AI solutions, helping customers navigate their cloud transformation journeys. Beyond work, he enjoys networking with fellow professionals and spending quality time with family.

    AWS Transform custom: Enterprise Code Modernization with the Learn-Scale-Improve Flywheel

    Post Syndicated from Venugopalan Vasudevan original https://aws.amazon.com/blogs/devops/aws-transform-custom-enterprise-code-modernization-with-the-learn-scale-improve-flywheel/

    Enterprise modernization has reached an inflection point. You can transform one repository easily. Existing tools, including AWS Transform custom, work well for individual repositories, and the process is understood. But what about 50 repositories? 100? 200? When you need to modernize at enterprise scale, transforming code is only part of the challenge. Coordinating people, capturing knowledge, and maintaining quality across your entire portfolio are also important.

    In this post, we explore how AWS Transform custom’s bulk automation capabilities address the enterprise coordination problem through intelligent learning and scaled execution. You will see how one customer reduced end-to-end modernization timelines from 7-12 weeks to 2.5 weeks, delivering a 3-5x reduction in delivery time and 10-20x reduction in total effort hours. Most importantly, you will learn how to start your own transformation journey immediately.

    The Coordination Problem at Enterprise Scale

    Ask any enterprise architect about their last major modernization initiative, and you will hear familiar stories. As an example, an enterprise software company needed to migrate a large legacy codebase to a modern platform. Their projection: 12 weeks of intensive work coordinating across multiple teams.
    The code transformation itself took days. The remaining weeks were consumed by the end-to-end activities surrounding it: orchestrating teams across time zones, ensuring consistent patterns across codebases with different histories, and managing dependencies so upstream changes did not break downstream systems. Teams tracked status through meetings and spreadsheets and captured tribal knowledge that existed only in senior developer heads.

    This is the enterprise coordination problem. When you scale from one repository to hundreds, coordination overhead explodes. Each additional repository adds not just its own complexity, but new integration points, edge cases, and unanticipated coordination requirements.

    The Hidden 70% Gap

    In enterprise engagements, we have observed that code transformation represents approximately 30% of the modernization effort. The remaining 70% include things like test generation, validation, comprehensive documentation, business analysis, and organizational coordination across hundreds of moving pieces.

    This gap explains why productivity gains from transformation tools rarely materialize. The tools handle code changes, but organizations still struggle with coordination, validation, and knowledge capture. The transformation is completed quickly, but the project takes months.

    Here is what we see: traditional approaches fail at enterprise scale because they treat each repository as an independent challenge. Teams repeat work across codebases, make inconsistent decisions, and lose learnings when developers move to different projects. Organizational knowledge remains trapped in individual heads rather than becoming reusable assets.
    A New Approach to Enterprise Modernization
    AWS Transform custom takes a different approach to enterprise modernization. Rather than repeating the same operation hundreds of times, the service learns from every execution and applies that knowledge to improve future transformations.

    The Learn-Scale-Improve Flywheel

    The workflow follows a deliberate progression designed to maximize learning while minimizing risk. It begins with a focused learn pilot, scales through bulk automation, and improves through deliberate review, creating a flywheel where each cycle produces better results than the last (Figure 1).

    Iterative transformation workflow with three stages: LEARN (interactive pilot, refine TD), SCALE (bulk execution, overnight processing), and IMPROVE (review and approve knowledge items). Arrows show the cycle: org knowledge captured flows from Learn to Scale, edge cases observed flow from Scale to Improve, and TD improves flows from Improve back to Learn.

    Figure 1: Learn Scale and Improve Flywheel for AWS Transform custom transformation

    Learn — You start with two to three representative repositories and execute transformations in interactive mode. You work directly with the AI agent, providing feedback on decisions and validating quality at each step. When the agent encounters ambiguity, it asks questions. You provide guidance, and the system captures that context. At the end of the pilot, you review the feedback and modify the transformation definition. The result is a transformation definition enhanced with your organizational knowledge, ready to scale.

    Scale — You shift to non-interactive mode for bulk execution. The system processes dozens or hundreds of repositories overnight without manual intervention, applying patterns learned during the pilot. It validates transformations using your build and test commands and tracks progress across your portfolio in real time. What previously required weeks of team coordination happens overnight. During execution, the system captures observations: new edge cases, unexpected patterns, and optimization opportunities the pilot did not encounter.

    Improve — After each round of bulk execution, you review the knowledge items the system captured during processing. These observations surface patterns and edge cases specific to repositories the pilot did not cover. You approve the valuable learnings, and your transformation definition improves for the next iteration. This review step ensures quality control. The system does not self-modify. Transformation owners decide which learnings get incorporated.

    The Scale-Improve cycle repeats. Each round of bulk execution generates insights that make the next round more effective. Transformation success rates increase, manual intervention decreases, and edge case handling improves with every iteration.

    This flywheel transforms how enterprises capture and share institutional knowledge. Transformation definitions are not automation scripts. They are organizational assets that encode how your company approaches specific modernization scenarios. When an architect defines a transformation strategy, that strategy becomes a reusable definition stored in your registry. When your team identifies best practices, those practices become embedded within the transformation definition and automatically apply across all repositories. Previously, when a senior developer left your team, that knowledge disappears with them. With AWS Transform custom, their expertise is captured in transformation definitions and knowledge items available to the entire organization. Individual expertise becomes an organizational capability.

    An Enterprise Customer Modernization Case Study

    These productivity gains are production outcomes, not theoretical projections. An enterprise software company needed to migrate a large volume of production-grade Control-M workflows to Apache Airflow, a modernization requiring both technical precision and consistency across a complex, interdependent codebase. Their estimate was 12 weeks of intensive coordination across multiple teams, with risk of inconsistency and integration failures.

    Using AWS Transform custom, the company executed an iterative learn-scale-improve workflow. During the pilot phase, they ran interactive transformations on representative repositories, reviewed results, and refined transformation definitions. With each iteration, transformation definitions improved in edge case handling and accuracy. They then shifted to non-interactive bulk execution across their portfolio and completed the full migration in 2.5 weeks.

    The validation achieved a 100% success rate across all workflows in scope. Edge case handling improved by 60% compared to the customer’s existing approach, and the transformed code demonstrated a 19% runtime performance improvement while meeting industry expert code quality standards. This proves that organizations can achieve both migration speed and production readiness, with 3-5x faster delivery timelines and 10-20x reduction in total effort hours compared to traditional approaches.

    Get Started: Transform Your Repository Portfolio

    AWS Transform custom bulk automation capabilities are available as a solution in this Github repo. Follow the learn-scale-improve workflow to begin your transformation journey.

    Prerequisites

    Before beginning, ensure you have:

    • An AWS account with AWS Transform custom access enabled
    • AWS CLI configured with appropriate credentials
    • Git installed on your local machine or CI/CD environment
    • IAM permissions for AWS Transform custom operations

    Your Implementation Path

    AWS Transform custom supports Java upgrades (e.g., 8 to 17, 17 to 21), Python migrations (e.g., 3.7 to 3.11), Node.js updates (e.g., 14 to 20), AWS SDK migrations (e.g., boto2 to boto3, SDK v1 to v2), and other transformations. Beyond these AWS-managed transformations, you can create custom transformation definitions for organization-specific standards, proprietary framework migrations, and architectural patterns unique to your environment.

    AWS Transform custom integrates naturally into your existing development processes. The CLI connects with CI/CD pipelines like Jenkins, GitLab CI, or GitHub Actions. Transformations create code in local Git branches that flow through your standard code review and merge processes. The web interface provides centralized visibility for tracking progress across teams. Validation commands execute automatically during transformation, ensuring code builds successfully and tests pass before changes are considered complete. At the end of the transformation, if validation criteria fail, the transformation is marked as failed.

    To accelerate your path to scaled execution, AWS provides an open-source sample repository that gives you a production-ready starting point for running transformations across multiple repositories and transformation definitions simultaneously. The aws-transform-custom-samples scaled execution repository includes scripts that orchestrate bulk execution, manage repository queuing, and handle status tracking across your portfolio. Rather than building orchestration from scratch, you clone the sample, configure it with your repository list and transformation definitions, and begin executing scaled transformations immediately.

    Conclusion

    Enterprise modernization at scale requires more than code transformation tools. The real challenges are coordination across teams, learning from execution, and capturing knowledge as organizational assets. AWS Transform custom learn-scale-improve workflow addresses these challenges through continual learning that improves quality with every execution, organizational knowledge capture that transforms tribal expertise into reusable assets, and bulk automation that scales consistently across hundreds of repositories. When the next critical security vulnerability requires framework updates across your repositories, or a new runtime version unlocks performance improvements, you respond in days rather than months — using transformation definitions you have already proven.

    Real customers have reduced delivery timelines by 3-5x and total effort hours by 10-20x, compressing modernization from months to weeks. These are not aspirational goals. They are production results from organizations using AWS Transform custom today.

    Begin Your Transformation Today

    Follow the learn-scale-improve workflow on two to three representative repositories, refine your transformation definitions, then scale across your portfolio.
    To dive deeper into AWS Transform custom bulk automation capabilities, explore these resources:

        • AWS Transform custom Documentation — Technical documentation covering all capabilities, API references, and integration guides: AWS Transform custom
        • Scaled Execution Sample Repository — Open-source scripts for running transformations across multiple repositories and transformation definitions: aws-transform-custom-samples
        • Transformation Registry — Discover AWS-managed transformations and create custom definitions: aws-transform-custom-samples

    Contact your AWS account team or visit the AWS Transform custom documentation to begin your journey.


    About the authors

    meghan-author

    Meghan Kothari

    Meghan Kothari is a Senior Technical Product Manager with the Customer Experience and Business Trends team, where he partners with AWS leadership on strategic deep dives to discover evolving trends in agentic AI-driven application development and modernization. His background as a solutions architect and full-stack developer gives him a unique hands-on perspective to help shape the developer experience. 

    Venu-author

    Venugopalan Vasudevan

    Venugopalan Vasudevan (Venu) is a Principal Specialist Solutions Architect at AWS, where he leads Agentic AI initiatives focused on AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

    grilli-author

    Rodney Grilli

    Rodney Grilli is a Principal Technologist at AWS, specializing in product and code modernization using agentic AI services. He builds solutions that help customers modernize their product portfolios and accelerate their transformations into AI-Native Enterprises.

    Automating Incident Investigation with AWS DevOps Agent and Salesforce MCP Server

    Post Syndicated from Rohit Sharma original https://aws.amazon.com/blogs/devops/automating-incident-investigation-with-aws-devops-agent-and-salesforce-mcp-server/

    This post was co-written with Ross Belmont, Senior Director, Rodrigo Duran, Strategist Director at Salesforce

    Every minute counts when managing a critical infrastructure incident. Organizations need to quickly identify issues, diagnose root causes, and implement solutions—all while keeping customers informed. AWS DevOps Agent changes this by automating investigation and response, reducing mean time to resolution (MTTR) from hours to minutes.

    In this post, you’ll learn how to integrate AWS DevOps Agent with Salesforce Hosted MCP Server to create an autonomous incident investigation workflow. This integration connects customer support cases directly to infrastructure diagnostics, reducing response times, and facilitating consistent incident resolution across your organization.

    The Challenge: The Cost of Manual Incident Investigation

    Customer complaints like “the website is slow” often trigger hours of investigation across distributed systems, fragmented telemetry, and multiple teams. Your customer support team lacks the deep infrastructure expertise to diagnose root causes, while your DevOps Engineers are constantly interrupted and pulled away from systematic improvements.

    This handoff between teams creates friction:

    • Increased mean time to detect (MTTD) – Issues sit in queues waiting for the right expert
    • Extended mean time to resolve (MTTR) – Manual investigation across Amazon CloudWatch, AWS CloudTrail, application logs, and deployment history is time-consuming
    • Context loss – Information gets lost in translation between support tickets and infrastructure analysis
    • Reactive problem solving – Teams spend time on symptoms rather than preventing recurring issues
    This diagram illustrates the traditional, manual incident response workflow before AWS DevOps Agent integration. It shows the friction-filled handoff process where a customer reports an issue to the support team, who then manually escalates it to DevOps engineers. The flow highlights pain points including increased mean time to detect (MTTD), extended mean time to resolve (MTTR), context loss between teams, and reactive problem-solving. The visual emphasizes how information gets lost in translation between support tickets and infrastructure analysis, with issues sitting in queues waiting for the right expert.

    Figure 1 – Manual Support Process without DevOps Agent

    AWS DevOps Agent integrated with Salesforce changes this paradigm by connecting support workflows directly to autonomous infrastructure investigation, eliminating manual handoffs and reducing investigation time.

    How It Works – A Seamless Flow from Customer Complaint to Infrastructure Diagnosis

    This diagram depicts the streamlined, automated incident response workflow enabled by AWS DevOps Agent integrated with Salesforce. It shows four key steps: case creation in Agentforce Service, autonomous investigation by DevOps Agent across AWS observability services, case enrichment with technical findings posted back to Salesforce, and preventative recommendations. The flow eliminates manual handoffs between support and engineering teams, connecting customer complaints directly to infrastructure diagnostics for faster resolution and consistent incident handling.

    Figure 2 – Automated Support Process with DevOps Agent

    1. Case Creation: Your customer reports an issue in Agentforce Service (e.g., “My Load Balancer is showing unavailable”). Salesforce Flow detects the new case and triggers the AWS DevOps Agent via an API or webhook call.
    2. Autonomous Investigation: DevOps Agent starts an investigation and identifies the root cause. The agent queries AWS observability services, third-party platforms like Splunk and Datadog, code repositories, and CI/CD pipelines. It builds a dynamic topology graph to map relationships between application resources.
    3. Case Enrichment: Investigation findings automatically post back to the Salesforce case, providing your support team with technical context and root cause analysis.
    4. Preventative Recommendations: The agent suggests architectural improvements to help prevent recurrence.

    Real-World Example: The Single Instance Outage

    The Incident

    A customer opens a case in Agentforce Service reporting an application as unavailable.

    Salesforce Agentforce Service interface displaying a customer-reported support case. The case details include the customer's complaint about an application being unavailable. This is the starting point of the automated investigation workflow, where a customer opens a case reporting a service disruption. The interface shows standard Salesforce case fields such as account information, incident description, and timing details that will be used by AWS DevOps Agent to initiate its autonomous infrastructure investigation.

    Figure 3 – Agentforce Service case details

    The Investigation

    Salesforce Flow triggers DevOps Agent when the case is created:

    1. Case Retrieval: The agent uses the Salesforce soql_query tool to retrieve case details, including the customer’s account, incident description, and timing. The tool is made available via Salesforce Hosted MCP.

      Salesforce soql_query tool, made available via Salesforce Hosted MCP, to retrieve case details from Salesforce. The query pulls information including the customer's account, incident description, and timing. This is the first step of the autonomous investigation, where the agent programmatically accesses Salesforce CRM data to understand the reported issue before beginning infrastructure diagnostics

      Figure 4 – Salesforce SOQL Query

    2. Topology Discovery: The agent maps the infrastructure and identifies all components of the application.
    3. CloudWatch Metrics Analysis: The agent examines metrics during the incident window and discovers the count of requests dropped to zero during the unavailability period.

      CloudWatch metrics analysis, providing additional detail on the request count data during the incident window. Together with Figure 5a, it forms the complete picture of the traffic pattern showing the drop to zero requests. The agent uses this telemetry data as quantitative evidence to support its root cause analysis, correlating the exact timing of the traffic drop with other events discovered during the investigation, such as CloudTrail administrative actions.

      CloudWatch metrics analysis performed by AWS DevOps Agent during the investigation. It displays a request count chart for the affected application during the incident window. The metrics reveal that the count of incoming requests dropped to zero during the unavailability period reported by the customer. This data point is critical evidence the agent uses to correlate the customer complaint with actual infrastructure behavior, confirming that the application was indeed unreachable during the reported timeframe.

      Figure 5 – Request Count Chart

    4. CloudTrail Event Analysis: The agent discovers a sequence of administrative actions that caused the downtime.

      AWS DevOps Agent analyzing CloudTrail events during the incident timeframe. The agent discovers a sequence of administrative actions that caused the application downtime. CloudTrail provides an audit trail of API calls made in the AWS account, and the agent examines these events to identify what infrastructure changes occurred around the time of the outage. This step is crucial for correlating operational events with the observed metrics drop, helping the agent build a timeline of the incident.

      Figure 6 – CloudTrail Analysis

    5. Root Cause Determination: The agent correlates the administrative actions with the metrics drop, identifying that an EC2 instance termination caused the outage.

      AWS DevOps Agent's root cause determination. The agent correlates the administrative actions found in CloudTrail with the CloudWatch metrics drop, identifying that an EC2 instance termination caused the outage. The findings show the specific sequence of events: an EC2 instance was terminated, which caused the application to become unavailable since it was running on a single instance without redundancy. This demonstrates the agent's ability to autonomously connect multiple data sources to pinpoint the exact cause of an incident.

      Figure 7 – Root Cause Details

    6. Case Update: The agent uses the Salesforce create_sobject_record tool to post findings to the case Activity feed. The tool is made available via Salesforce Hosted MCP.

    The Result

    Your Salesforce case now contains a comprehensive root cause analysis with timeline, affected resources, and contributing factors.

    Salesforce Agentforce Service case after AWS DevOps Agent has posted its investigation findings. The case now contains a comprehensive root cause analysis including a timeline of events, affected resources, and contributing factors. The support team can see the technical diagnosis directly within their familiar Salesforce interface without needing to escalate to engineering. This demonstrates the case enrichment step where investigation results flow back to Salesforce automatically via the Hosted MCP Server.

    Figure 8 – Agentforce Service case updated with root cause

    The Mitigation Plan

    The agent generates an actionable mitigation plan showing how to prevent recurrence.

    The actionable mitigation plan generated by AWS DevOps Agent after completing its root cause analysis. The plan outlines specific recommendations for preventing recurrence of the incident, such as implementing redundancy and auto-scaling. Rather than just identifying what went wrong, the agent proactively suggests architectural improvements. This transforms incident response from a purely reactive process into an opportunity for systematic infrastructure improvement, helping organizations build more resilient systems over time.

    Figure 9 – Mitigation Plan

    The agent also provides step-by-step remediation instructions that you can apply immediately. Due to length, this shows a portion of the plan.

    Showing a portion of the step-by-step remediation instructions generated by AWS DevOps Agent. These instructions provide specific, immediately actionable guidance that operations teams can follow to implement the recommended mitigations. The instructions go beyond high-level recommendations to include concrete implementation steps. Due to length, only a portion of the full plan is shown, demonstrating the depth and specificity of the agent's remediation guidance for preventing future occurrences of the identified issue.

    Figure 10 – Step by Step Mitigation instructions

    Technical Implementation

    Prerequisites: Before implementing this integration, verify you have:

    1. Agentforce Service with Salesforce Hosted MCP Server enabled
    2. AWS DevOps Agent Space configured in your AWS account
    3. Amazon CloudWatch and AWS CloudTrail enabled for observability
    4. Infrastructure resources tagged for topology mapping (optional)
    5. Familiarity with Salesforce Flow Builder for workflow automation

    This integration requires configuration in both Salesforce and AWS. The following steps provide an overview of the setup process.

    1. Create Agent Space: Set up a DevOps Agent Space in your AWS account with appropriate IAM roles and permissions.
    2. Integrate Observability Tools: Connect your operational tools like Splunk, Datadog, or New Relic to provide the agent with telemetry data.
    3. Connect Code Repositories: Link GitHub, GitLab, or AWS CodeCommit to enable the agent to correlate incidents with recent deployments.
    4. Build Topology Mapping: Tag your infrastructure resources, so the agent focuses on components relevant to your application.
    5. Add Skills: Configure the agent with instructions to direct the investigation – for example, to update Agentforce Service cases when investigations are complete.

    Highlighted below are the key setup steps:

    Create Agent Space

    An Agent Space defines the AWS accounts, integrations, and access controls for your DevOps Agent investigations. When you create your Agent Space, configure a skill that instructs the agent to post investigation findings back to Salesforce cases.
    AWS DevOps Agent Space configuration interface where an agent skill is being set up for Salesforce integration. The skill provides specific instructions directing the agent to update the originating Agentforce Service case when an investigation completes. This configuration step is part of the technical implementation, defining the agent's workflow behavior. Skills tell the agent what actions to take, in this case posting investigation findings back to the Salesforce case that triggered the investigation.

    Figure 11 – Agent Skill for Salesforce

    The skill provides specific instructions for the agent’s workflow – in this case, directing it to update the originating Agentforce Service case when the investigation completes.

    Salesforce Hosted MCP Server Setup

    The Salesforce Hosted MCP Server enables AWS DevOps Agent to query case data and post investigation findings back to Salesforce. Configure the MCP Server in your Salesforce org using the following steps. For complete instructions, see the Salesforce documentation and the Salesforce Hosted MCP GitHub Repository.

    Add the Salesforce Hosted MCP Server to Your Agent Space

    In the AWS Console, register the Salesforce MCP Server with your Agent Space. This connection allows DevOps Agent to query Salesforce case data and post investigation findings.

    After registration, test by manually triggering an investigation from the AWS Console. Instruct the agent to retrieve case details from Salesforce and post the root cause analysis back to the case.
    When configuring MCP tools, follow best
    security practices.
    AWS DevOps agent Operator Console interface for manually triggering a DevOps Agent investigation. It demonstrates how to instruct the agent to retrieve case details from Salesforce and post root cause analysis back to the case. This manual trigger is used during initial setup and testing before automating the workflow with Salesforce Flow. The interface shows the investigation prompt and configuration, including the connection to the Salesforce Hosted MCP Server for bidirectional communication between AWS and Salesforce.

    Figure 12 – Starting an Investigation

    In the next step, you’ll automate this workflow using Salesforce Flow, so investigations trigger automatically when cases are created.

    Using Salesforce Flows

    Salesforce Flows automate the connection between case creation and DevOps Agent investigations. Flow is a no-code automation tool that uses a visual drag-and-drop interface (Flow Builder) to automate business processes.

    Configure a Flow trigger on your Case object to invoke DevOps Agent automatically when cases are created.

    Salesforce Flow trigger configuration on the Case object. The trigger is set to fire automatically when new cases are created, initiating the DevOps Agent investigation workflow without manual intervention. This is the automation component that connects Salesforce case creation to AWS DevOps Agent, replacing the manual process of escalating issues to engineering teams. The Flow Builder's visual interface shows the trigger conditions that determine when the automated investigation should begin.

    Figure 13 – Salesforce Trigger

    The Flow calls the DevOps Agent webhook with case details including the customer account, incident description, and timing. This triggers an autonomous investigation without requiring manual handoff to engineering teams. Due to length, this shows a portion of the Flow.

    Salesforce Flow that automates the connection between case creation and AWS DevOps Agent investigations. The Flow calls the DevOps Agent webhook with case details including customer account, incident description, and timing. Built using Salesforce's no-code Flow Builder with its visual drag-and-drop interface, this automation triggers autonomous infrastructure investigation without requiring manual handoff to engineering teams. Due to length, only a portion of the full Flow is displayed.

    Figure 14 – Salesforce Flow

    For implementation details and example code, see this Code repository

    Connecting Salesforce Flow to AWS DevOps Agent

    Configure how Salesforce Flow invokes the DevOps Agent webhook. Choose one of three integration approaches based on your requirements:

    1. Option 1: External Service (Recommended for simplicity)External Service Integrate with AWS services using SigV4 (AWS Signature Version 4) authentication through Named Credentials. This no-code approach is the fastest way to establish the connection.
    2. Option 2: Apex Class (Recommended for custom logic)Create an Apex class that your Flow calls to invoke the webhook. This approach provides flexibility to add custom business logic or error handling before triggering investigations.

    Results and Impact

    This integration transforms incident response by connecting customer support directly to autonomous infrastructure investigation:

    Faster Incident Resolution: Autonomous investigation reduces mean time to resolution (MTTR) by eliminating manual log analysis. The agent detects and diagnoses issues immediately when cases are created, providing 24/7 coverage across time zones.

    Reduced Manual Effort: SRE teams focus on systematic improvements instead of responding to individual incidents. Support teams receive technical insights without escalating to engineering, and every investigation follows the same thorough process.

    Improved Customer Experience: Customers receive detailed root cause analysis within minutes of reporting an issue. This transparency builds trust, and the agent’s architectural recommendations help prevent recurring problems.

    Organizational Learning: Every investigation is documented and searchable, creating a knowledge base of incident patterns. The agent identifies recurring issues across cases and suggests infrastructure improvements to address root causes.

    Conclusion

    Connecting AWS DevOps Agent with a Salesforce Hosted MCP Server creates an autonomous investigation workflow that eliminates manual handoffs between support and engineering teams. This integration reduces mean time to resolution through instant analysis, improves customer experience with rapid root cause updates, and enables proactive prevention through pattern recognition.

    About the Authors

    This blog post was authored by:

    Conor Manton author photo

    Conor Manton

    Conor Manton is a Principal Technical Account Manager at AWS, based in San Francisco. He works with strategic enterprise customers to accelerate their cloud journey, with a focus to operationalize AI-powered workflows to drive business outcomes.

    Ross Belmont author photo

    Ross Belmont

    Ross Belmont is a Senior Director of Product Management focused on integrations, with more than 15 years of experience in the Salesforce ecosystem.

    Rohit Sharma author photo

    Rohit Sharma

    Rohit Sharma is a Senior Technical Account Manager at AWS Enterprise Support, based in New York. He partners with strategic enterprise customers to optimize their cloud operations, leveraging AI and automation to reduce operational overhead and improve incident response at scale.

    Rodrigo Duran author photo

    Rodrigo Duran

    Rodrigo Duran is an AI Deployment Strategist Director at Salesforce. Based in São José dos Campos, São Paulo, Brazil. He partners with strategic customers globally to bridge the gap between technical strategy and business impact, scaling AI-powered deployments on the Salesforce platform.

    A technical walkthrough of multicloud full-stack security using AWS Security Hub Extended

    Post Syndicated from Matt Meck original https://aws.amazon.com/blogs/security/a-technical-walkthrough-of-multicloud-full-stack-security-using-aws-security-hub-extended/

    Building on our recent announcement of AWS Security Hub Extended —our full-stack enterprise security offering — we want to show you how we’re simplifying security procurement and operations for your multicloud environments. Whether you’re a security architect evaluating solutions or a CISO looking to streamline vendor management, this post walks through the streamlined experience that transforms how you acquire, deploy, and manage end-to-end enterprise security solutions across endpoint, identity, email, network, data, browser, cloud, AI, and security operations. Security Hub Extended brings together AWS security services with carefully curated security partners. Delivering better outcomes together through unified procurement, billing, and operations that significantly reduce vendor management overhead so you can focus on what matters most: protecting your organization.

    The challenge we’re addressing

    Security teams today spend too much time on vendor management, evaluating services, negotiating contracts, and managing multiple billing cycles instead of focusing on what matters most: managing risk. But the procurement challenge runs even deeper. Until now, customers really only had one option: sign multi-year agreements based solely on proof-of-concept testing and estimated annual usage. This forces organizations to commit budget before they can validate whether a solution will work for them at scale.

    AWS Security Hub Extended transforms this procurement model. Security Hub Extended offers customers the option to get started with pay-as-you-go pricing and no commitments, so they can move fast and validate solutions in their actual environment. After they’ve confirmed a solution works at scale, they can then align their vendor strategy and sign longer-term commitments for even more favorable pricing.

    Security Hub Extended provides a curated set of carefully chosen partner solutions with competitive pricing, unified billing through your AWS account, and seamless integration. Our initial launch partners, selected by customers for their proven value, include 7AI, Britive, CrowdStrike, Cyera, Island, Noma, Okta, Oligo, Opti, Proofpoint, SailPoint, Splunk, Upwind, and Zscaler.

    Getting started with Security Hub Extended

    AWS Security Hub consolidates threat analytics from Amazon GuardDuty, vulnerability management from Amazon Inspector, and sensitive data discovery from Amazon Macie, correlating these signals with Security Hub Exposure findings to determine overall risk, reachability, and assumability. Security Hub Extended builds on this foundation by adding curated partner solutions, extending these unified security operations across your entire organization including multicloud, on-premises, and endpoint environments. If you’re already using Security Hub, you can navigate directly to the Extended plan section.

    Getting started with Security Hub is straightforward. From the AWS Management Console, search for Security Hub to start the onboarding walkthrough. If you’re not already a Security Hub customer, you can quickly complete onboarding by designating an AWS organization delegated administrator (DA) account. You can then centrally enable and manage Security Hub across your entire organization’s accounts and AWS Regions from a single location (see Introduction to AWS Security Hub). After you’ve onboarded, navigate to the Extended plan section to add curated partner solutions.

    Figure 1- Security Hub centralized configuration

    Figure 1: Security Hub centralized configuration

    From this single interface, you can enable detection and response capabilities across your entire organization, provide granular configurations at the organizational unit or member account level, select specific Regions, and turn individual features on or off as needed.

    Understanding risk through attack paths

    The Security Hub risk correlation engine identifies potential exposures by correlating threats, vulnerabilities, and misconfigurations to reveal how they connect and could lead to compromise of critical resources.

    Figure 2 - Security Hub exposure attack path visualization

    Figure 2: Security Hub exposure attack path visualization

    The attack path visualization in the preceding figure reveals critical insights including upstream root causes and blast radius, showing the potential impact if a threat actor exploits a vulnerability. You can use this visualization to focus on fixing the root cause rather than addressing symptoms. For example, updating one security group configuration can eliminate the entire attack path, cutting off all downstream exposure.

    Accessing Security Hub Extended

    You can find Security Hub Extended, shown in the following figure, in the left navigation pane under Management in your Security Hub delegated administrator (DA) account; Security Hub Extended will only be visible from the delegated administrator account. The Extended plan brings curated third-party security solutions directly into the Security Hub experience. Because Extended is built into Security Hub, there’s no separate console to manage. You discover, subscribe to, and operate curated partner solutions from the same place you manage enterprise security, delivering unified operations across your entire security estate.

    Figure 3- Security Hub Extended partners

    Figure 3: Security Hub Extended partners


    Transparent, competitive pricing consolidated with Security Hub

    Unlike traditional third-party engagements that require lengthy negotiations, private pricing deals, and multi-year commitments, Security Hub Extended offers complete pricing transparency. Every partner solution displays clear, competitive monthly pay-as-you-go rates billed directly with Security Hub requiring no commitments. For example, Cloud Security from Upwind costs $3.75 per resource per month, and Identity Security from Okta costs $20 per user per month.

    All Security Hub Extended offerings are also eligible for AWS Enterprise Discount Program (EDP) discounts that will be applied automatically. If you have an existing AWS enterprise discount agreement, those discounts automatically apply to Security Hub Extended offerings, further reducing your effective costs. All partner solutions you deploy through Security Hub Extended appear on your consolidated AWS bill, no separate invoices or payment processes.

    Streamlined onboarding

    Adopting curated partner solutions through Security Hub Extended is straightforward. Choose View Product to initiate an automated workflow. Depending on the solution, you’ll either be directed to the partner onboarding console or provide information for the partner to guide you through their onboarding process tailored to your environment.

    Billing begins only after you’re fully activated on the partner solution and starts automatically, no additional action is required to benefit from the unified billing. If you’re already using one of the curated partner solutions, transitioning to Security Hub Extended for consolidated billing and flexible pricing won’t disrupt your current services. Now, instead of receiving separate invoices for each partner in addition to Amazon Inspector, GuardDuty, and Security Hub CSPM you get one unified bill through Security Hub. This consolidates visibility to support better understanding of spend and to manage cost.

    Unified operations

    Security Hub Extended unifies security operations by consolidating findings from AWS and curated partner solutions. All findings use the Open Cybersecurity Schema Framework (OCSF) for consistency, without the need for complex data normalization, transformation, and extract, transform, and load (ETL) processes.

    When you deploy solutions such as CrowdStrike, Noma, and Upwind alongside Splunk and 7AI through Security Hub Extended, security findings automatically flow into Security Hub and then seamlessly route to Splunk and 7AI. All in OCSF format so your security team can focus on responding to threats, not managing pipelines, so you can quickly identify and respond to security risks that span boundaries—from endpoint compromises to cloud infrastructure—without spending valuable time on manual integration work.

    The full-stack security vision

    Security Hub Extended represents a shift in how you discover, procure, and build comprehensive security programs. Instead of managing dozens of vendor relationships, negotiating separate contracts, agreeing to multi-year annual commitments, and integrating disparate tools, you now have one procurement process through AWS, one bill with transparent competitive pay-as-you-go pricing, one console for unified security operations, one support channel for AWS Enterprise Support customers, and one schema (OCSF) for all security findings. The result: reduced security risk, improved team productivity, and a more unified approach to security operations across your enterprise.

    Get started

    Try Security Hub Extended today and experience how simplified procurement and unified operations can transform your security program. Security Hub Extended is generally available globally in all AWS commercial Regions where Security Hub is available. We’ve also published a walk through video to further explain how Security Hub Extended works.

    It’s still Day 1, but we’re iterating fast, so share your feedback with us on AWS re:Post for Security Hub or through your AWS Support contacts and watch for future blog posts on our progress.


    Matt Meck

    Matt Meck

    Matt is a Worldwide Security Specialist at Amazon Web Services, based in New York, with 10 years of experience in the tech industry. For the past 4 years at AWS, he’s focused on Detection and Response, helping solve complex security challenges in the rapidly evolving security space. He works closely with product teams, customers, partners, and field teams to deliver effective security solutions.


    Michael Fuller

    Michael Fuller

    Michael has been with AWS for 16 years and led product for AWS Security Services for 11 years. Michael has 29 years in the industry and held several roles in product management, business development, and software development for IBM, Cisco, and Amazon. Michael has a Bachelor’s of Science in Computer Engineering from the University of Arizona and an MBA from the University of Washington.