Tag Archives: Technical How-to

Using Apache Sedona with AWS Glue to process billions of daily points from a geospatial dataset

Post Syndicated from Ruan Roloff original https://aws.amazon.com/blogs/big-data/using-apache-sedona-with-aws-glue-to-process-billions-of-daily-points-from-a-geospatial-dataset/

Data strategy can use geospatial data to provide organizations with insights for decision-making and operational optimization. By incorporating geospatial data (such as GPS coordinates, points, polygons and geographic boundaries), businesses can uncover patterns, trends, and relationships that might otherwise remain hidden across multiple industries, from aviation and transportation to environmental studies and urban planning. Processing and analyzing this geospatial data at scale can be challenging, especially when dealing with billions of daily observations.

In this post, we explore how to use Apache Sedona with AWS Glue to process and analyze massive geospatial datasets.

Introduction to geospatial data

Geospatial data is information that has a geographic component. It describes objects, events, or phenomena along with their location on the Earth’s surface. This data includes coordinates (latitude and longitude), shapes (points, lines, polygons), and associated attributes (such as the name of a city or the type of road).

Key types of geospatial geometries (and examples of each in parentheses) include:

  • Point – Represents a single coordinate (a weather station).
  • MultiPoint – A collection of points (bus stops in a city).
  • LineString – A series of points connected in a line (a river or a flight path).
  • MultiLineString – Multiple lines (multiple flight routes).
  • Polygon – A closed area (the boundary of a city).
  • MultiPolygon – Multiple polygons (national parks in a country).

Geospatial datasets come in different formats, each designed to store and represent different types of geographic information. Common formats for geospatial data are vector formats (Shapefile, GeoJSON), raster formats (GeoTIFF, ESRI Grid), GPS formats (GPX, NMEA), web formats (WMS, GeoRSS) among others.

Core concepts of Apache Sedona

Apache Sedona is an open-source computing framework for processing large-scale geospatial data. Built on top of Apache Spark, Sedona extends Spark’s capabilities to handle spatial operations efficiently. At its core, Sedona introduces several key concepts that enable distributed spatial processing. These include Spatial Resilient Distributed Datasets (SRDDs), which allow for the distribution of spatial data across a cluster, and Spatial SQL, which provides a familiar SQL-like interface for spatial queries. Some of the core capabilities of Apache Sedona are:

  • Efficient spatial data types like points, lines and polygons.
  • Spatial operations and functions such as ST_Contains (check if point is inside of a polygon), ST_Intersects (check if point is inside of a polygon), ST_H3CellIDs (geospatial indexing system developed by Uber, return the H3 cell ID(s) that contain the given point at the specified resolution).
  • Spatial joins to combine different spatial datasets.
  • Integration with Spark SQL (geospatial functions to run spatial SQL queries).
  • Spatial indexing techniques, such as quad-trees and R-trees, to optimize query performance.

For more information about the functions available in Apache Sedona, visit the official Sedona Functions documentation.

Use case

This use case consists of a global air traffic visualization and analysis platform that processes and displays real-time or historical aircraft tracking data on an interactive world map. Using unique aircraft identifiers from the International Civic Aviation Organization (ICAO), the system ingests trajectory records containing information such as geographic position (latitude and longitude), altitude, speed, and flight direction, then transforms this raw data into two complementary visual layers. The Flight Tracks Layer plots the routes traveled by each aircraft individually, allowing for the analysis of specific trajectories and navigation patterns. The Flight Density Layer uses hexagonal spatial indexing (H3) to aggregate and identify regions of higher air traffic concentration worldwide, revealing busy air corridors, aviation hubs, and high-density flight zones.

The dataset used for this use case is historical flight tracker data from ADSB.lol. ADSB.lol provides unfiltered flight tracker with a focus on open data. Data is also freely available via the API. The data contains a file per aircraft, a JSON gzip file containing the data for that aircraft for the day.

This is a JSON trace file format sample:

{
    icao: "0123ac", // hex id of the aircraft
    timestamp: 1609275898.495, // unix timestamp in seconds since epoch (1970)
    trace: [
        [ seconds after timestamp,
            lat,
            lon,
            altitude in ft or "ground" or null,
            ground speed in knots or null,
            track in degrees or null, (if altitude == "ground", this will be true heading instead of track)
            flags as a bitfield: (use bitwise and to extract data)
                (flags & 1 > 0): position is stale (no position received for 20 seconds before this one)
                (flags & 2 > 0): start of a new leg (tries to detect a separation point between landing and takeoff that separates flights)
                (flags & 4 > 0): vertical rate is geometric and not barometric
                (flags & 8 > 0): altitude is geometric and not barometric
             ,
            vertical rate in fpm or null,
            aircraft object with extra details or null,
            type / source of this position or null,
            geometric altitude or null,
            geometric vertical rate or null,
            indicated airspeed or null,
            roll angle or null
        ],
    ]
}

For this use case, this is a simplified schema of the dataset after processing:

  • icao - Unique aircraft identifier
  • timestamp - Epoch timestamp of the observation (converted to readable format)
  • trace.lat / trace.lon - Latitude and longitude of the aircraft
  • trace.altitude - Aircraft altitude
  • trace.ground_speed - Ground speed
  • geometry - Geospatial geometry of the observation point (Point)

Solution overview

This solution enables aircraft tracking and analysis. The data can be visualized on maps and used for aviation management and safety applications. The process begins with data acquisition, extracting the compressed JSON files from TAR archives, then transforms this raw data into geospatial objects, aggregating them into H3 cells for efficient analysis. The processed data schema includes ICAO aircraft identifiers, timestamps, latitude/longitude coordinates, and derived fields such as H3 cell identifiers and point counts per cell. This structure allows detailed tracking of individual flights and aggregate analysis of traffic patterns. For visualization, you can generate density maps using the H3 grid system and create visual representations of individual flight tracks. The architecture data flow is as follows:

  • Data ingestion – Aircraft observation data stored as JSON compressed files in Amazon Simple Storage Service (Amazon S3).
  • Data processing – AWS Glue jobs using Apache Sedona for geospatial processing.
  • Data visualization – Spark SQL with Sedona’s spatial functions to extract insights and export data to visualize the information in a map on Kepler.gl.

The following figure illustrates this solution.
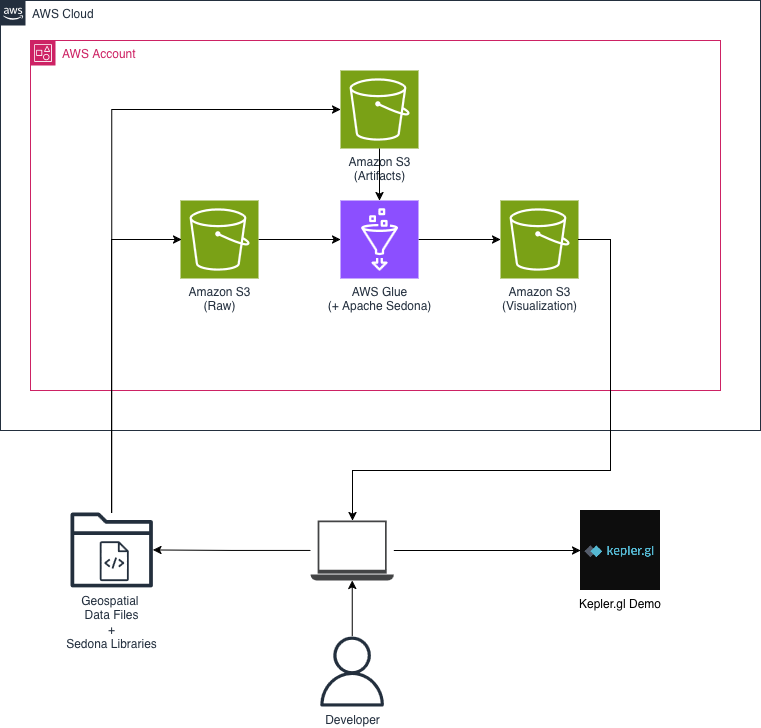
AWS architecture diagram showing a geospatial data processing pipeline.

Prerequisites

You will need the following for this solution:

Solution walkthrough

From now on, executing the next steps will incur costs on AWS. This step-by-step walkthrough demonstrates an approach to processing and analyzing large-scale geospatial flight data using Apache Sedona and Uber’s H3 spatial indexing system, using AWS Glue for distributed processing and Apache Sedona for efficient geospatial computations. It explains how to ingest raw flight data, transform it using Sedona’s geospatial functions, and index it with H3 for optimized spatial queries. Finally, it also demonstrates how to visualize the data using Kepler.gl. For data processing, it is possible to use both Glue scripts and Glue notebooks. In this post, we will focus only on Glue scripts.

Upload the Apache Sedona libraries to Amazon S3

  1. Open your OS terminal command line.
  2. Create a folder to download the Sedona libraries and name it jar.
    
    	# Create a directory for the Sedona libraries (JARs files)
    	mkdir jar
    	# Go to the folder JARs folder
    	cd jar
    	
  3. Download the Apache Sedona libraries.
    
    	# Download required Sedona libraries (JARs files)
    	wget https://repo1.maven.org/maven2/org/apache/sedona/sedona-spark-shaded-3.5_2.12/1.7.1/sedona-spark-shaded-3.5_2.12-1.7.1.jar
    	wget https://repo1.maven.org/maven2/org/datasyslab/geotools-wrapper/1.7.1-28.5/geotools-wrapper-1.7.1-28.5.jar
    	
  4. Upload the Sedona libraries (JARs files) to Amazon S3. In this example, we use the S3 path s3://aws-blog-post-sedona-artifacts/jar/.
    
    	# Upload the JARs files to Amazon S3 bucket
    	aws s3 cp . s3://blog-sedona-artifacts-<account_number>-<aws_region>/jar/ --recursive
    	
  5. Your Amazon S3 folder should now look similar to the following image:
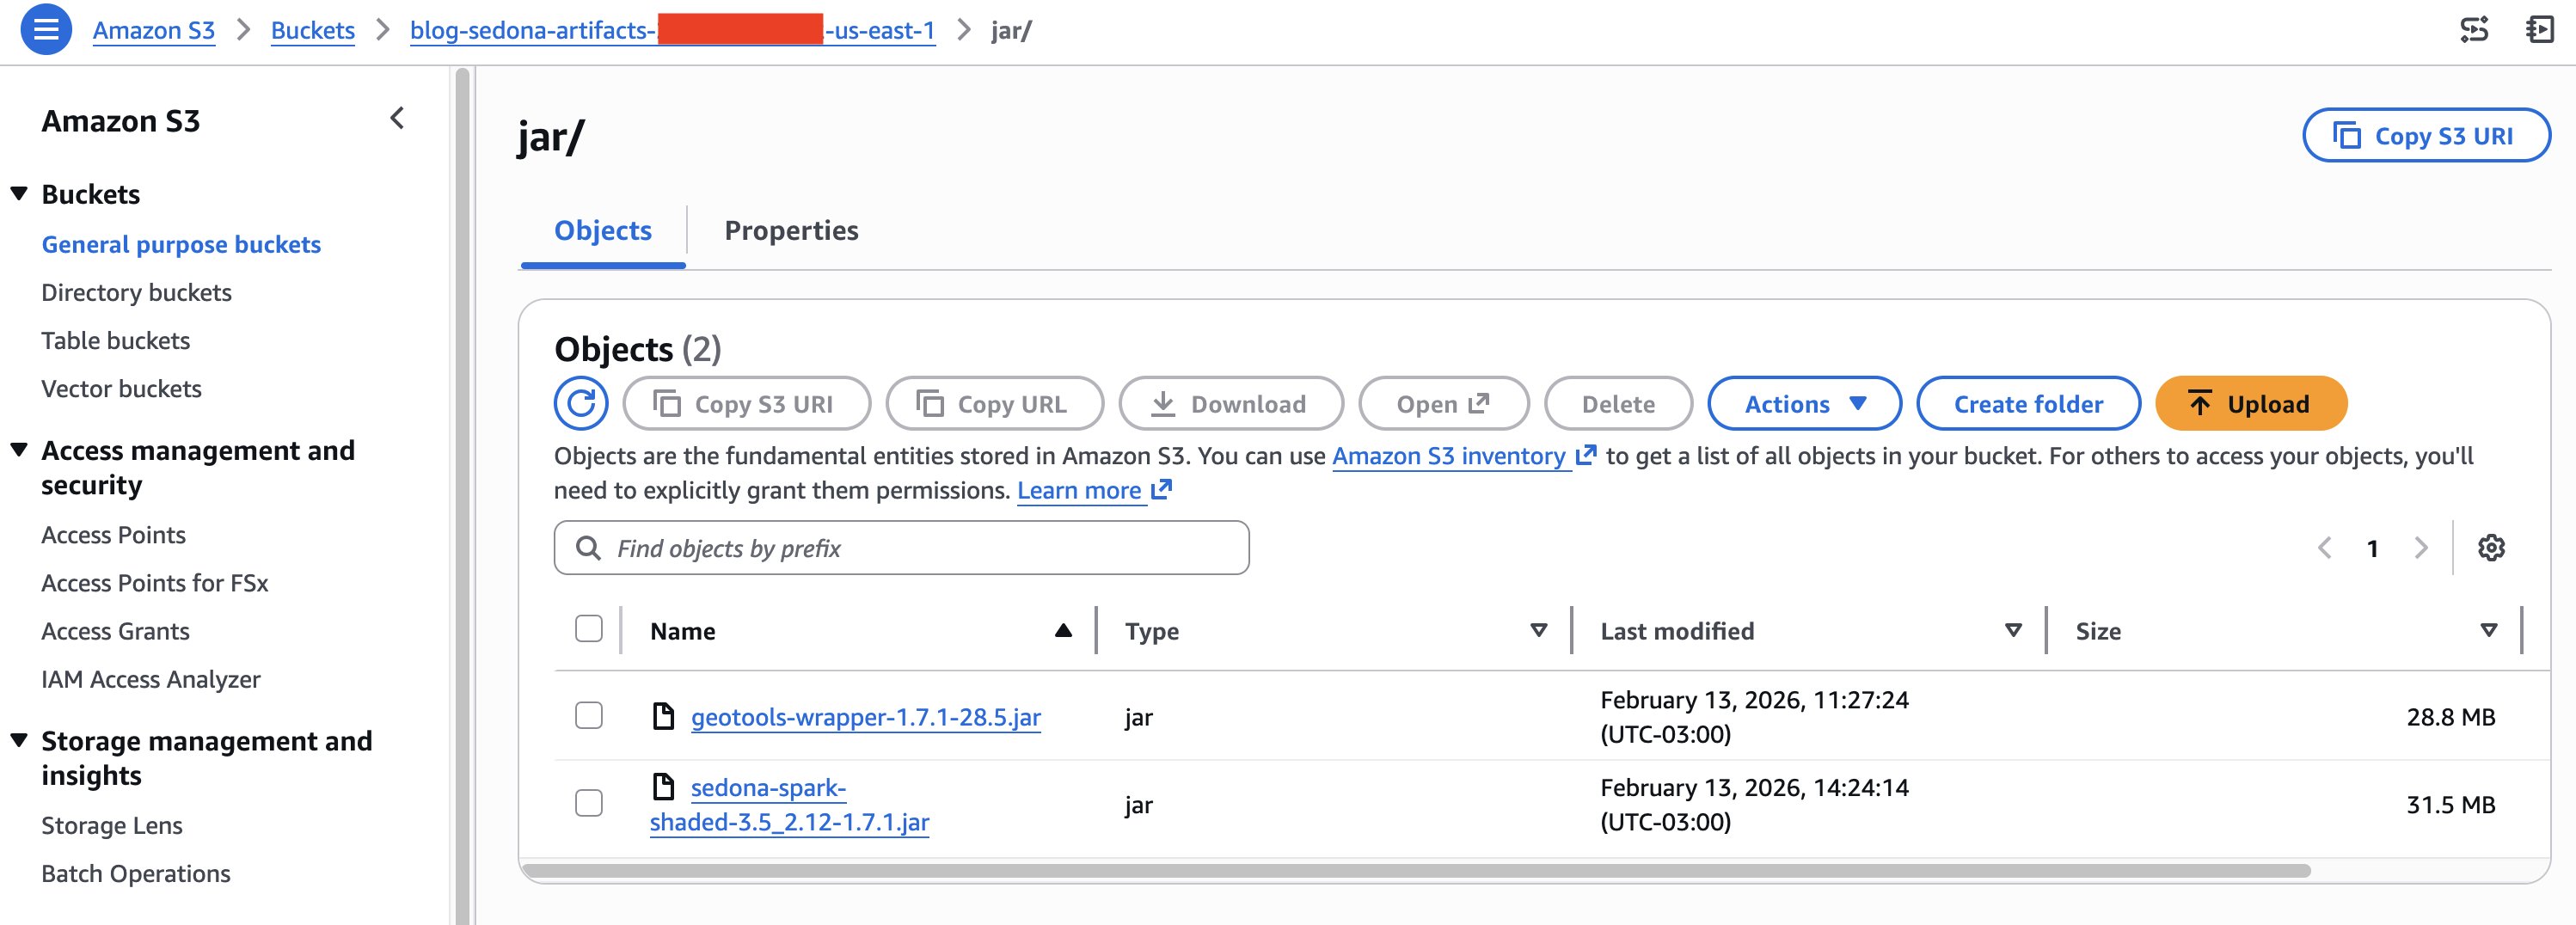
Amazon S3 console screenshot displaying the jar folder contents in blog-sedona-artifacts bucket.

Download and upload the geospatial data to Amazon S3

  1. Open your OS terminal command line.
  2. Create a folder to download the flight files and name it adsb_dataset.
    		# Create a directory for download the geospatial flight files
    		mkdir adsb_dataset
    		# Go to the folder for geospatial flight files
    		cd adsb_dataset
    	
  3. Download the flight files data from adsblol GitHub repository.
    	# Download the geospatial flight files in the folder created
    	wget https://github.com/adsblol/globe_history_2025/releases/download/v2025.05.29-planes-readsb-prod-0tmp/v2025.05.29-planes-readsb-prod-0tmp.tar.aa
    	wget https://github.com/adsblol/globe_history_2025/releases/download/v2025.05.29-planes-readsb-prod-0tmp/v2025.05.29-planes-readsb-prod-0tmp.tar.ab
    	
  4. Extract the flight files.
    	# Combine the two the tar files together
    	cat v2025.05.29* >> combined.tar
    	# Extract the json flight files from the tar file
    	tar xf combined.tar
    	
  5. Copy the flight files to Amazon S3. In this case, we are using the S3 folder: s3://blog-sedona-nessie-<account_number>-<aws_region>/raw/adsb-2025-05-28/traces/.
    	# Copy the json flight files to Amazon S3
    	aws s3 cp ./traces/ s3://blog-sedona-nessie-<account_number>-<aws_region>/raw/adsb-2025-05-28/traces/ --recursive
    	
  6. Your Amazon S3 folder should now look similar to the following image.
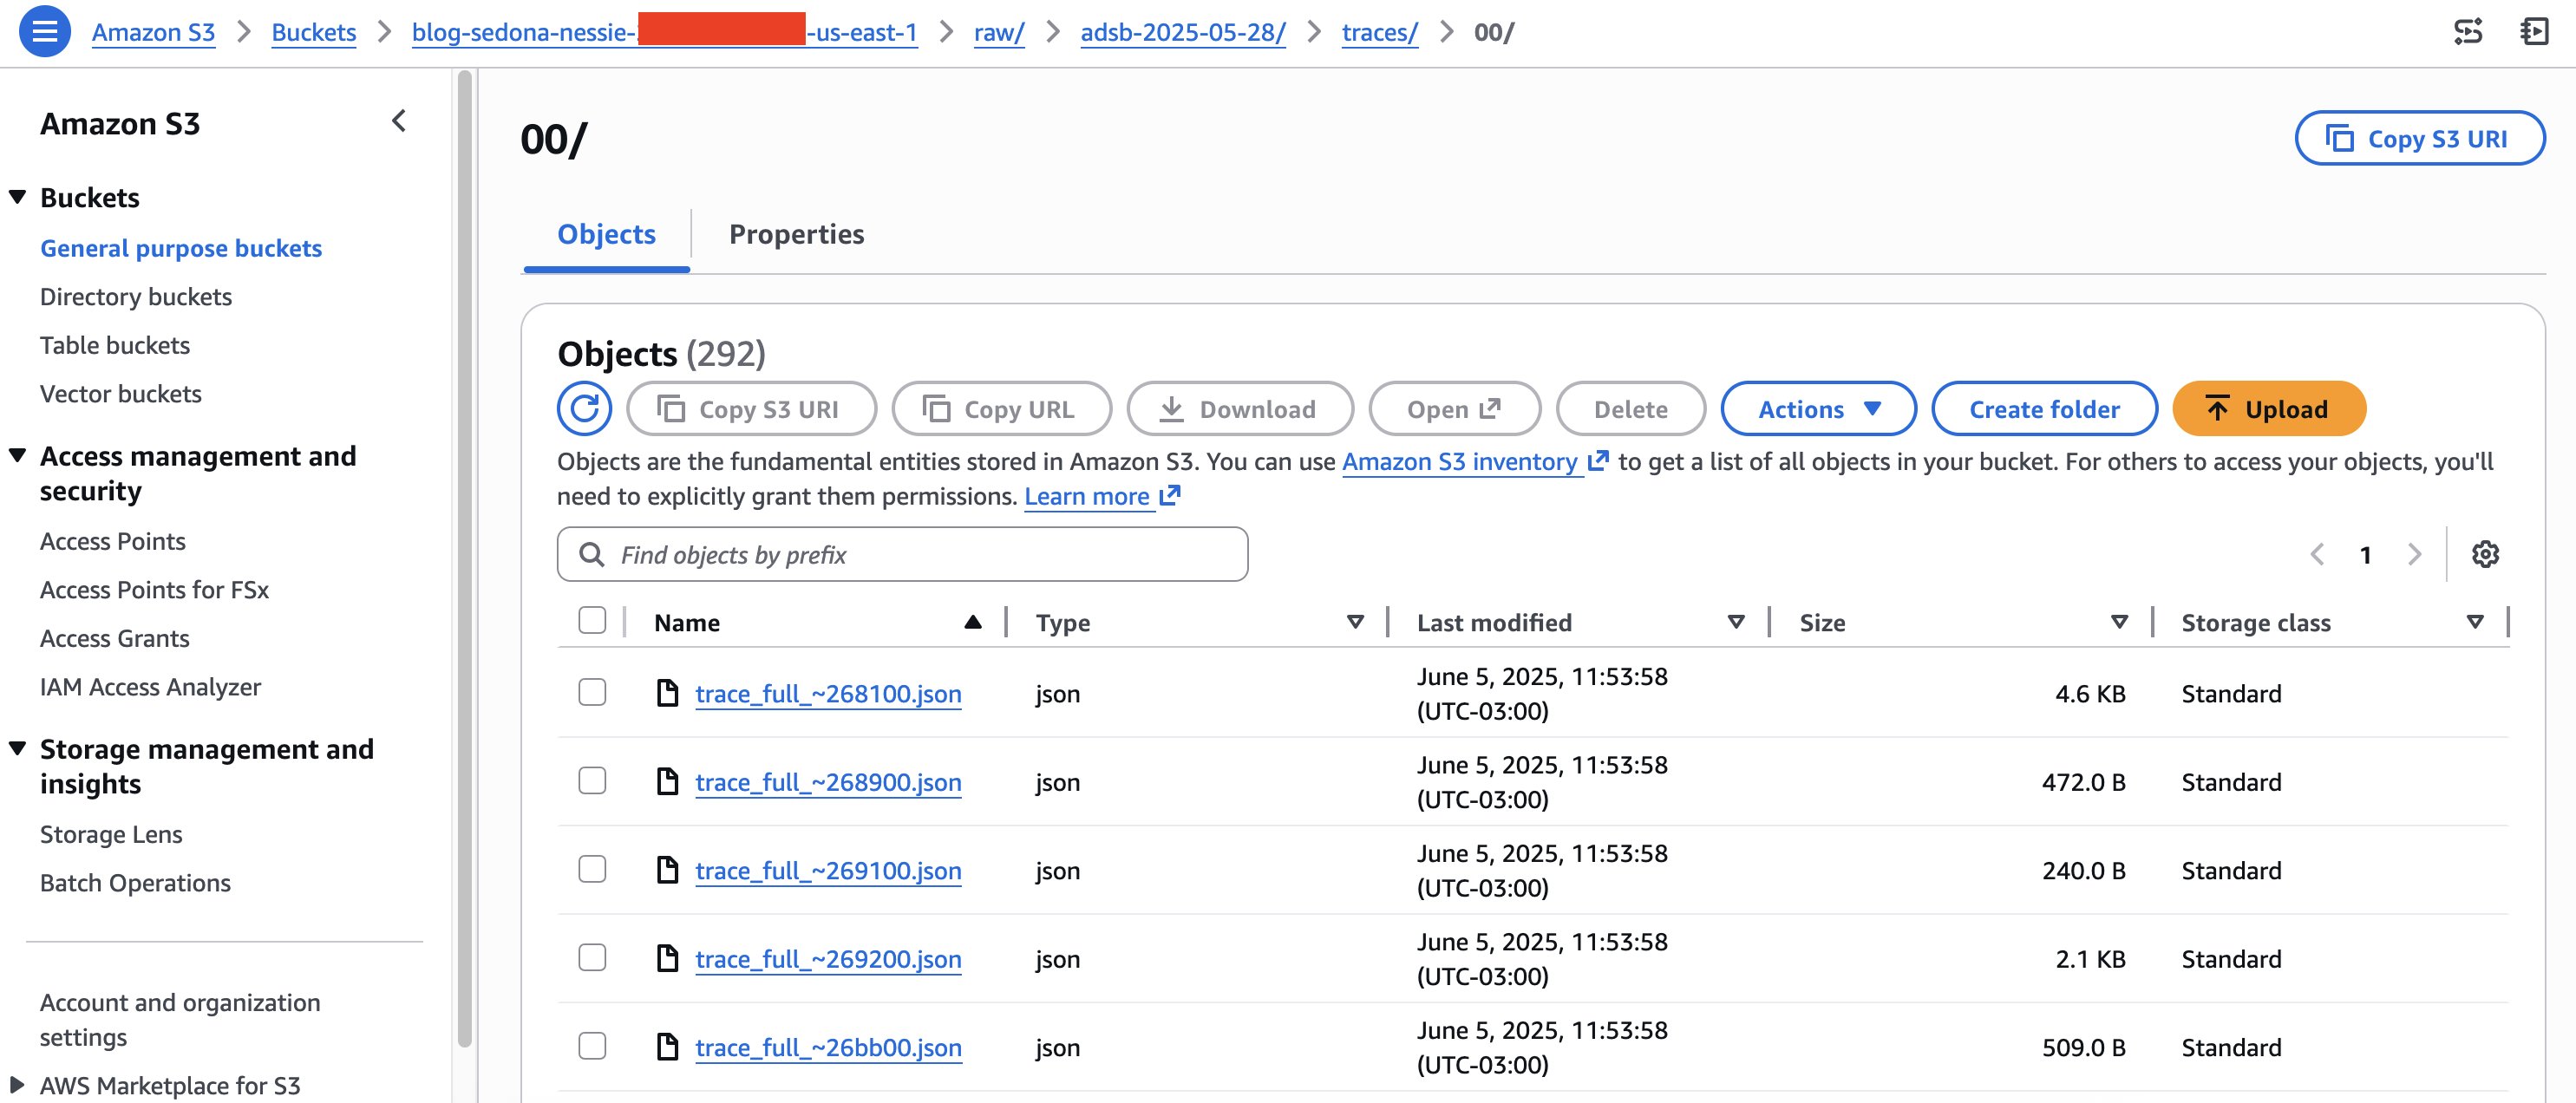
Amazon S3 console showing JSON trace files in the path raw/adsb-2025-05-28/traces/00/.

Create an AWS Glue job and set up the job

Now, we are ready to define the AWS Glue job using Apache Sedona to read the geospatial data files. To create a Glue job:

  1. Open the AWS Glue console.
  2. On the Notebooks page, choose Script editor.
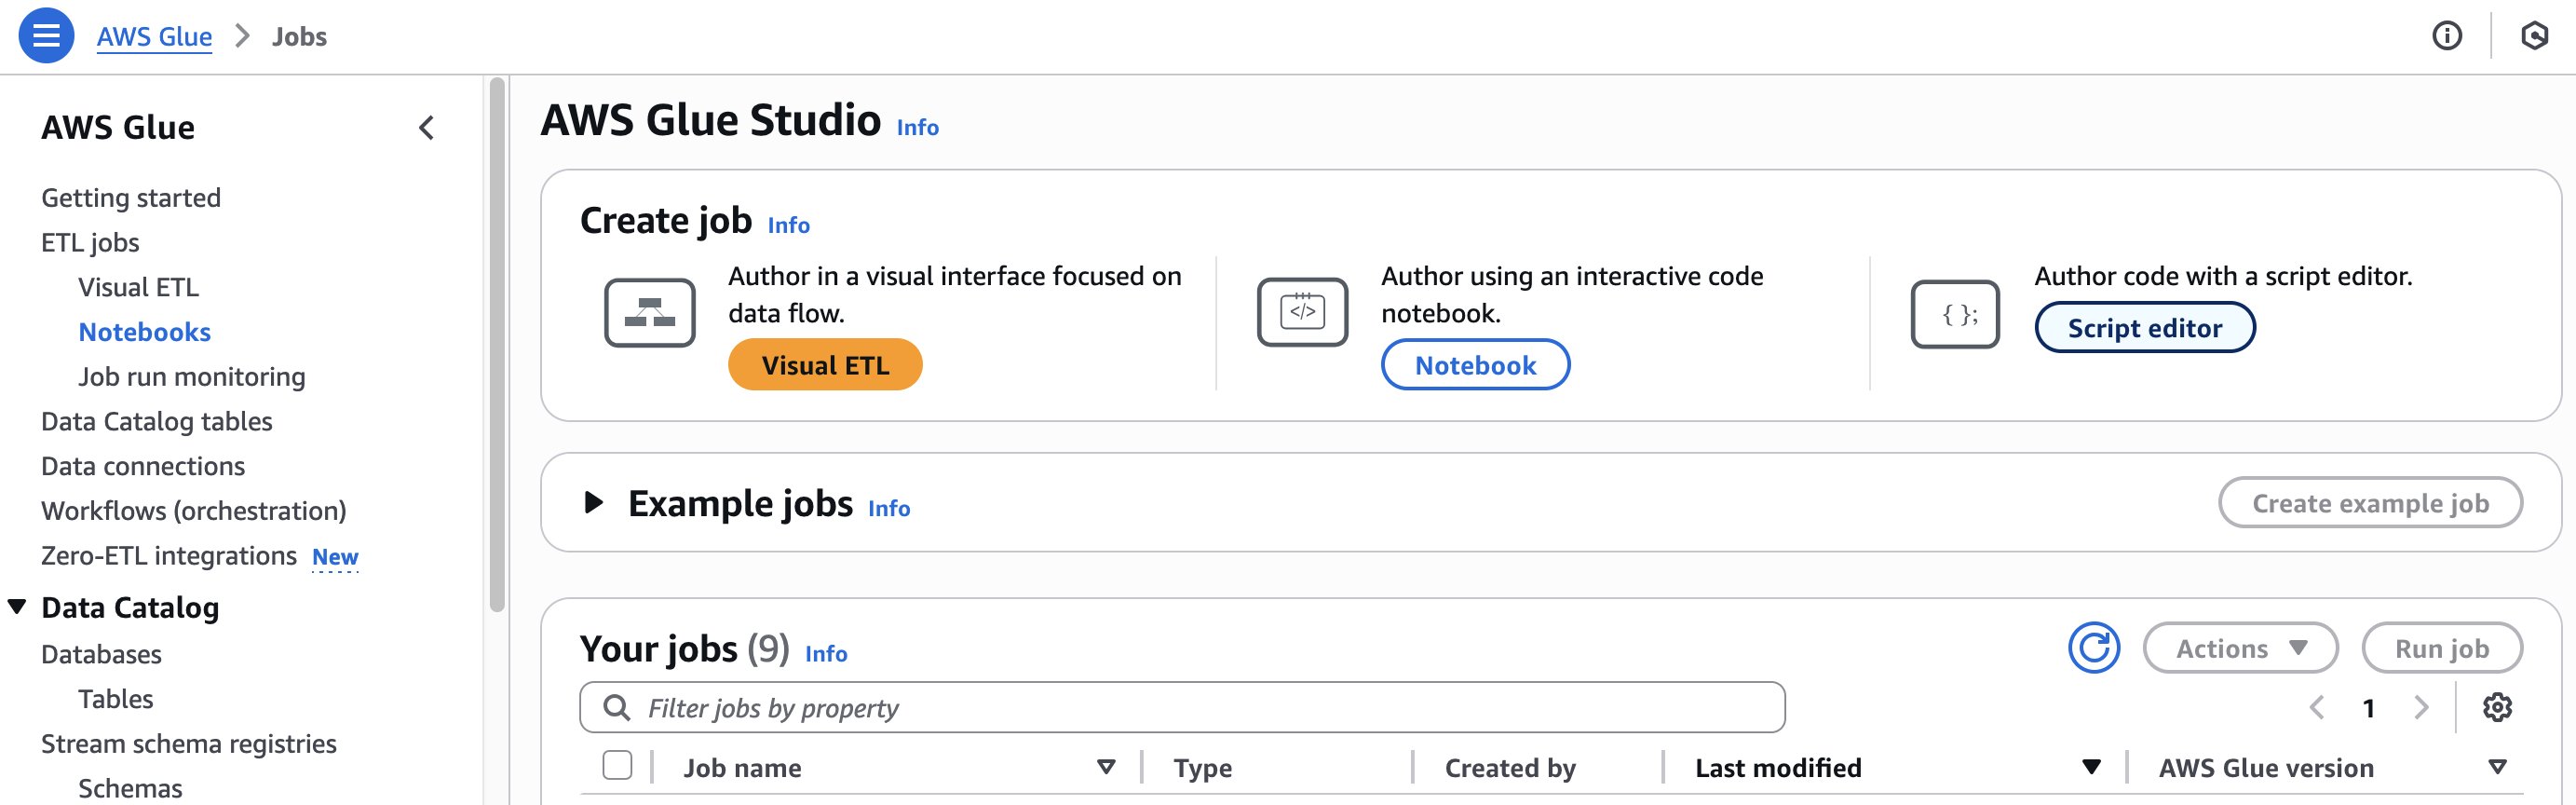
AWS Glue Studio jobs creation interface showing three job creation methods: Visual ETL with data flow interface, Notebook for interactive coding, and Script editor for code authoring

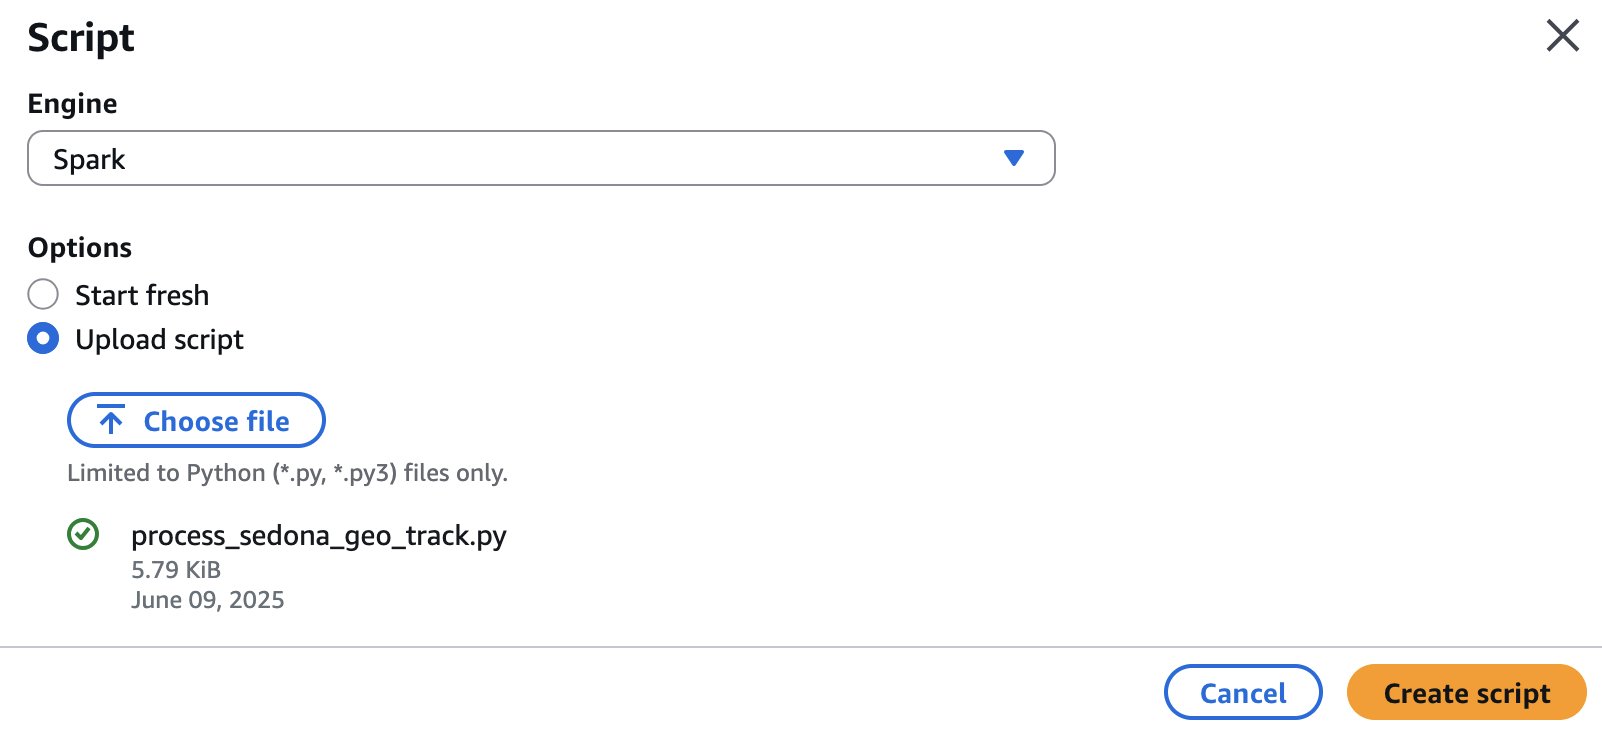
  1. On the Script screen, for the engine, choose Spark, then select the option Upload script.
  2. Choose Choose file. Find the process_sedona_geo_track.py file, then choose Create script.

Script creation dialog box with Spark engine selected. Upload script option is active, showing successfully uploaded file process_sedona_geo_track.py.

  1. Rename the job from Untitled to process_sedona_geo_track.
  2. Choose Save.
  3. Now, let’s set up the AWS Glue job. Choose Job Details.
  4. Choose the IAM Role created to be used with Glue. For this example, we use blog-glue.
  5. Set the Glue version to Glue 5.0 and the Worker type as needed. For this example, G.1X is sufficient, but we use G.2X to speed up processing.
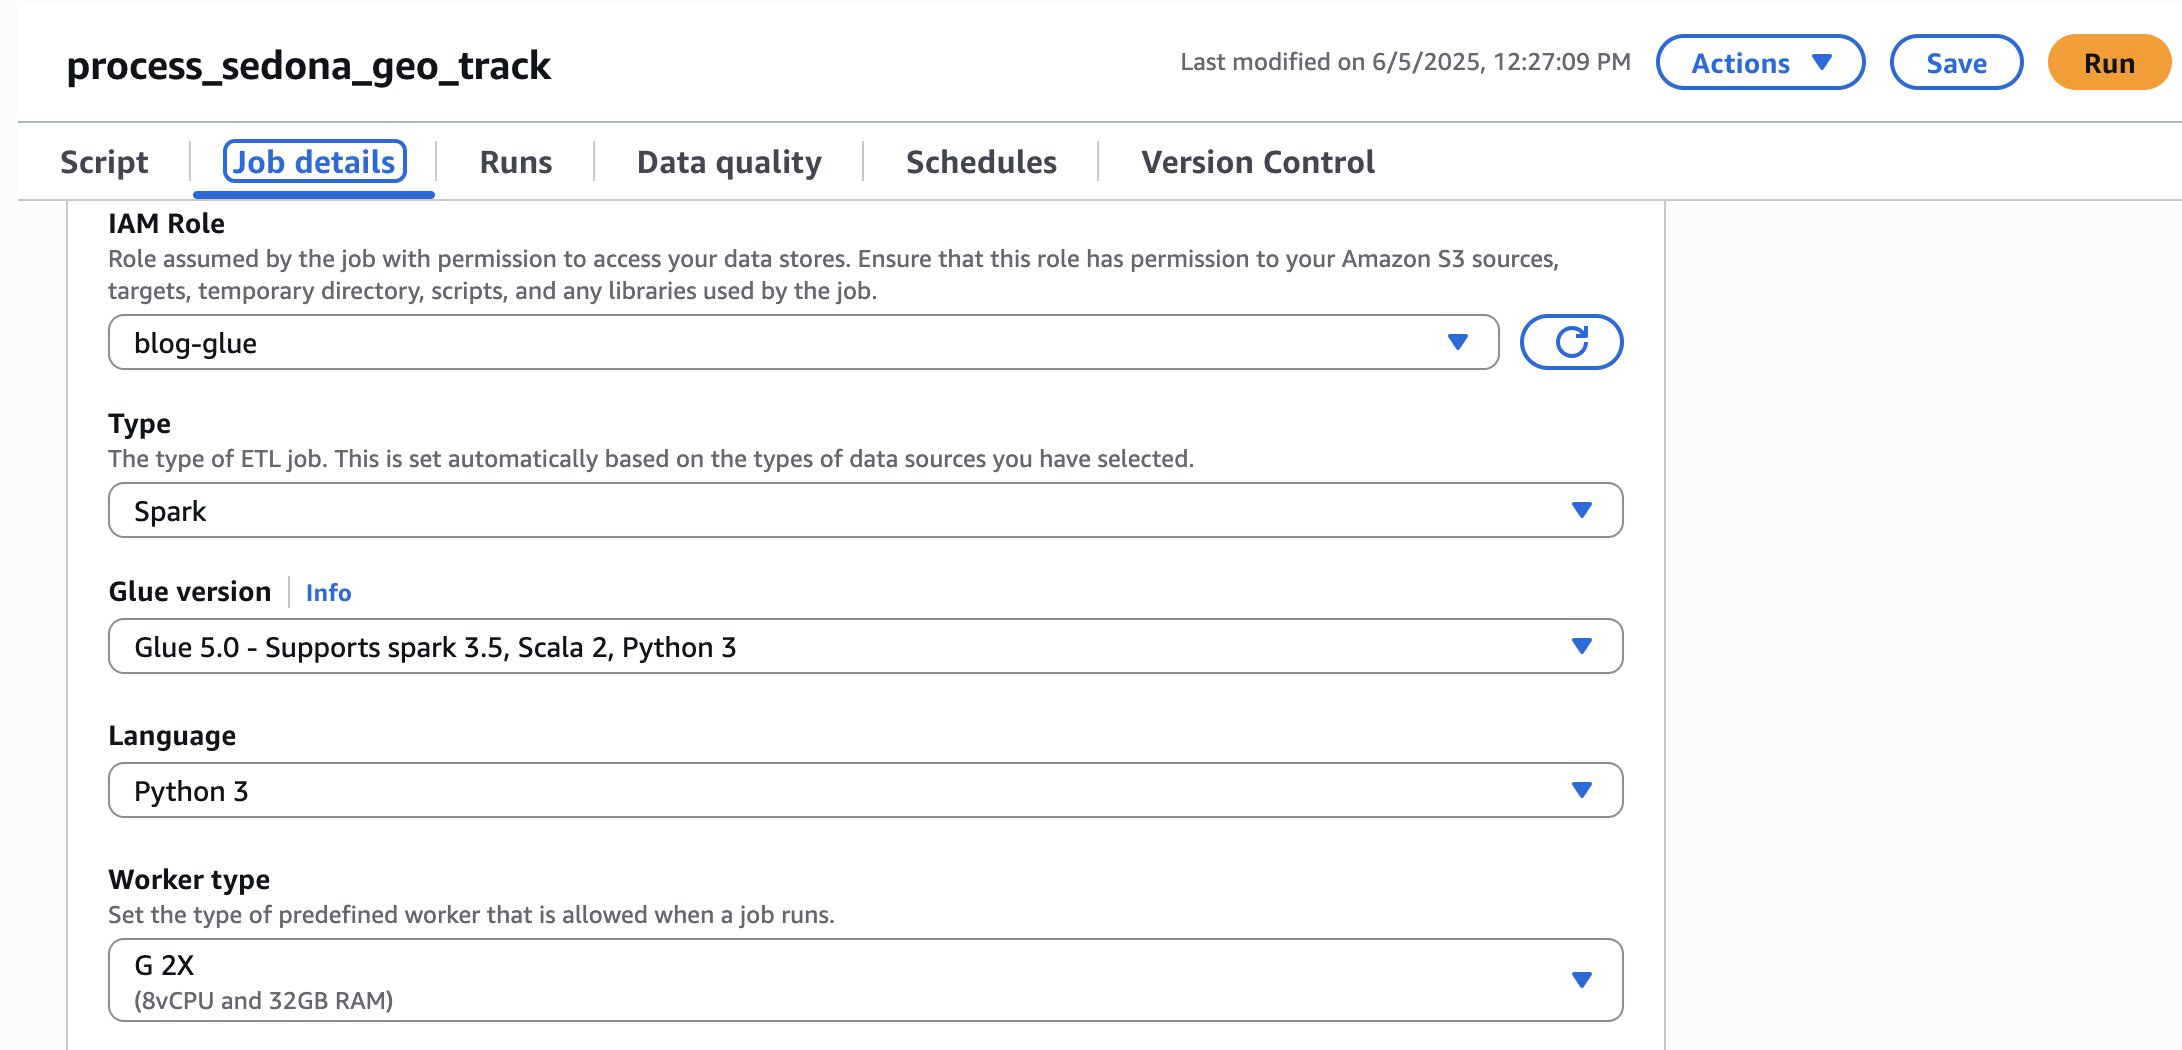
AWS Glue job details configuration page for process_sedona_geo_track.

  1. Now, let’s import the libraries for Apache Sedona.
  2. In the Dependent JARs path, type the path of the JAR files for Apache Sedona that you uploaded in the preceding steps. For this example, we used s3://blog-sedona-artifacts-<account_number>-<aws_region>/jar/sedona-spark-shaded-3.5_2.12-1.7.1.jar,s3://blog-sedona-artifacts-<account_number>-<aws_region>/jar/geotools-wrapper-1.7.1-28.5.jar
  3. In Additional Python modules path, enter the modules for Apache Sedona: apache-sedona==1.7.1,geopandas==0.13.2,shapely==2.0.1,pyproj==3.6.0,fiona==1.9.5,rtree==1.2.0
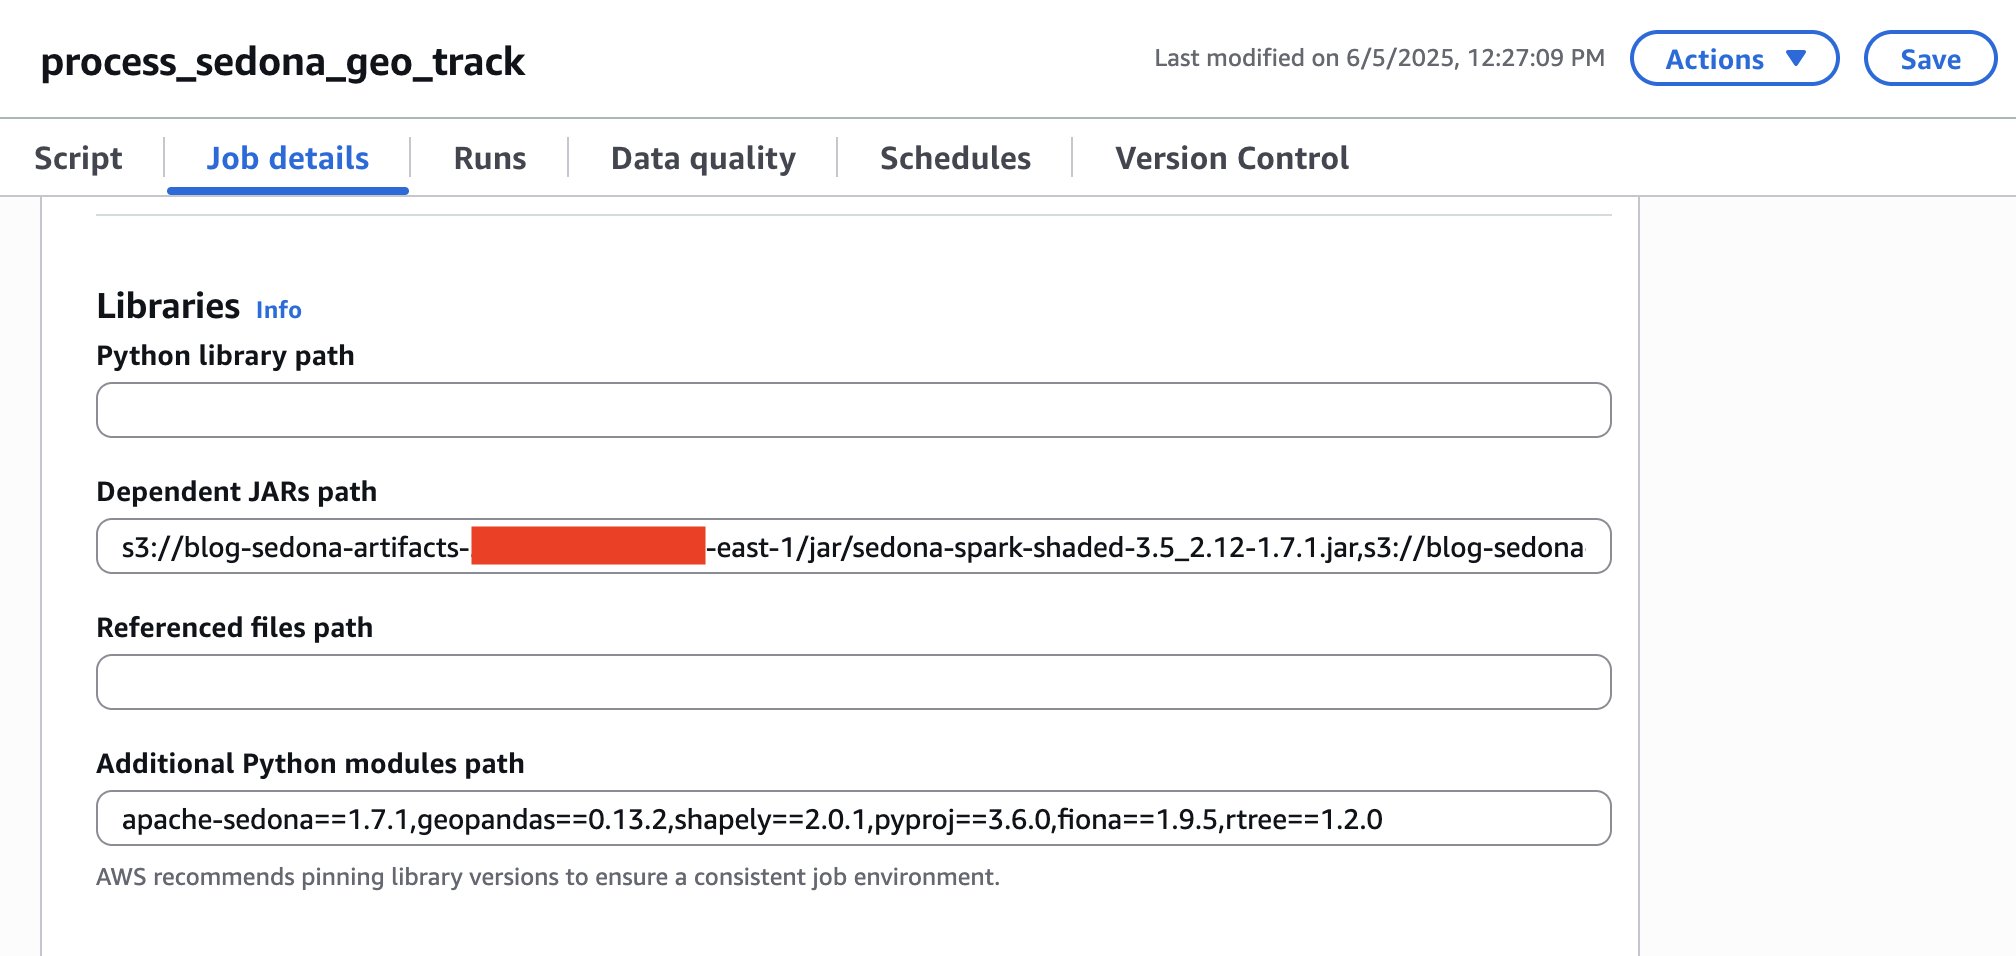
ob libraries configuration section showing Dependent JARs path pointing to S3 bucket.

  1. In the Job parameters section, in the Key field, type —BUCKET_NAME. For its Value, enter your bucket name. In this example, ours is blog-sedona-nessie-<account_number>-<aws_region>.
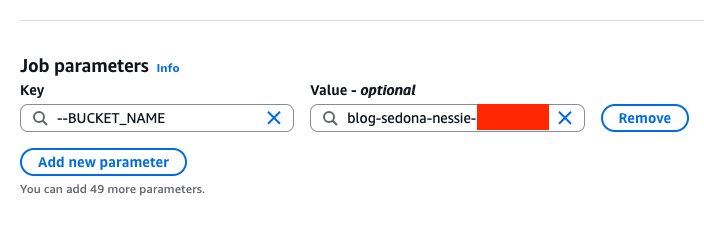
ob parameters configuration interface showing key-value pair with --BUCKET_NAME parameter.

  1. Choose Save.

Processing the geospatial flights data

Before we run the job, let’s understand how the code works. First, import the Apache Sedona libraries:

import json 
import gzip 
from sedona.spark import SedonaContext

Next, initialize the Sedona context using an existing Spark session:

sedona = SedonaContext.create(spark)

After that, create a function for handling compressed JSON data:

def parse_gzip_json(byte_content):
        try:
            decompressed = gzip.decompress(byte_content)
            return json.loads(decompressed.decode('utf-8'))
        except Exception as e:
            print(f"Error during gzip parse: {str(e)}")
            return None

Add a function to transform raw tracking data into a structured format suitable for a valid coordinates process:

def flatten_records(json_obj):
    records = []
    if "trace" in json_obj and isinstance(json_obj["trace"], list):
        for point in json_obj["trace"]:
            if len(point) >= 3:
                lat, lon = float(point[1]), float(point[2])
                if -90 <= lat <= 90 and -180 <= lon <= 180:
                    records.append(Row(
                        icao=json_obj.get("icao", None),
                        timestamp=json_obj.get("timestamp", None),
                        lat=lat,
                        lon=lon
                    ))
    return records

The flat_rdd variable applies these functions to the structured data from the original gzipped JSON. Each element in this RDD is a Row object representing a single data point from an aircraft’s trace, with fields for ICAO, timestamp, latitude, and longitude.

flat_rdd = raw_rdd.map(lambda x: parse_gzip_json(x[1])).filter(lambda x: x is not None).flatMap(flatten_records)

The ADSB trace files contain a deeply nested JSON structure where the trace field holds an array of mixed-type arrays, compressed in Gzip format. For this specific case, developing a UDF represented one of the most practical and efficient solutions. Since Gzip is a non-splittable format, Spark is unable to parallelize processing, constraining both methods to a single worker per file and processing the data multiple times across JVM decompression, full JSON parsing, and subsequent re-parsing operations. The UDF bypasses all of this by reading raw bytes and doing everything in a single Python pass: decompress → parse → extract → validate, returning only the small set of needed fields directly to Spark.

The Spark SQL query processes geographic trace data using the H3 hexagonal grid system, converting point data into a regularized hexagonal grid that can help identify areas of high point density. A resolution of 5 was adopted, producing hexagons of approximately 253 km² (roughly the same size as the city of Edinburgh, Scotland, which is approximately 264 km²), for its ability to effectively capture route density patterns at the city and metropolitan level.

h3_traces_df = spark.sql("""
WITH base_h3 AS (
    SELECT
        ST_H3CellIDs(geometry, 5, false)[0] AS h3_index,
        lat,
        lon
    FROM traces
)
SELECT
    COUNT(*) AS num, -- Count points in each H3 cell
    h3_index,
    AVG(lon) AS center_lon,
    AVG(lat) AS center_lat
FROM base_h3
GROUP BY h3_index
""")

Finally, this code prepares the datasets for visualization purposes. The first dataset is based on the aircraft unique identifier. The complete dataset for a single day can contain more than 80 million data points. A random sampling rate of 0.1% was applied, which proves sufficient to illustrate route density patterns without overwhelming the Kepler.gl browser renderer. The second dataset aggregates trace points into hexagonal spatial cells (result from the query above).

points_viz_sampled = df_points.select(
    col("icao"), # Aircraft unique identifier (24-bit address)
    col("timestamp").cast("double").alias("timestamp"),
    col("lat").cast("double").alias("lat"),
    col("lon").cast("double").alias("lon")
).sample(False, 0.001)

h3_viz_csv = h3_traces_df.select(
    col("num").alias("point_count"),
    col("h3_index").cast("string").alias("h3_index"),
    col("center_lon"),
    col("center_lat")
)

Now that we understand the code, let’s run it.

  1. Open the AWS Glue console.
  2. On the ETL jobs >> Notebooks page, choose the job name process_sedona_geo_track.
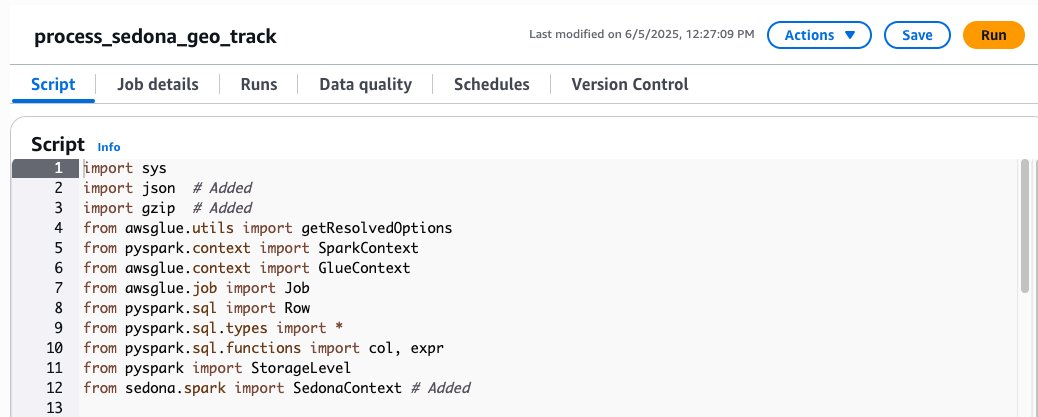
  3. Choose Run.

Python script editor showing import statements for process_sedona_geo_track job.

  1. Now, it is possible to monitor the job by choosing the Runs tab.
  2. It may take a few minutes to run the entire job. It took nearly 8 minutes to process approximately 2.50 GB (67,540 compressed files) with 20 DPUs. After the job is processed, you should see your job with the status Succeeded.
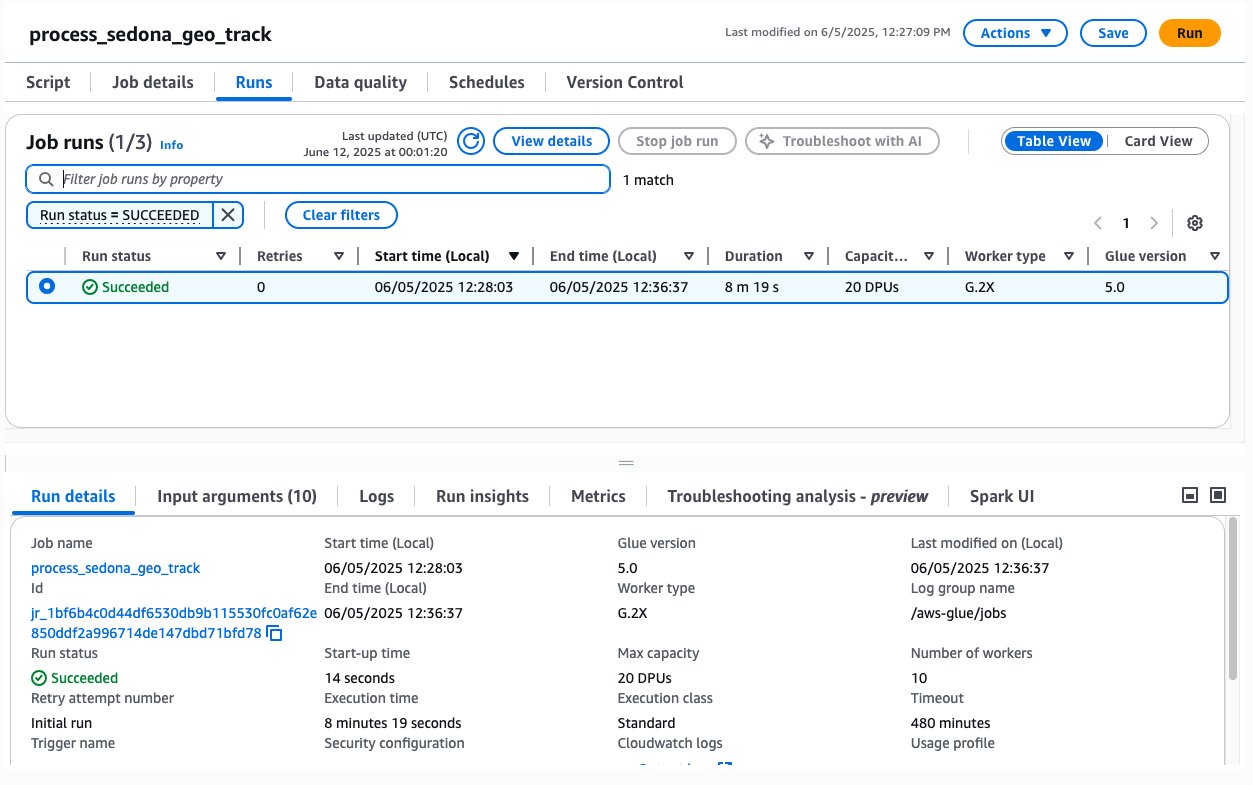
Job runs monitoring dashboard showing successful execution on June 5, 2025, running from 12:28:03 to 12:36:37 with 8 minutes 19 seconds duration.

Now your data should be saved for a preview visualization demo in a folder named s3://blog-sedona-nessie-<account_number>-<aws_region>/visualization/.

Performance insights

The workload characterization of this job reveals a CPU-intensive profile, primarily because of the processing of small binary files with GZIP compression and subsequent JSON parsing. Given the inherent nature of this pipeline, which includes Python UDF serialization and partial single-partition write stages, linear scaling does not yield proportional performance gains. The following table presents an analysis of AWS Glue configurations, evaluating the trade-off between computational capacity, execution duration, and associated costs:

Duration Capacity (DPUs) Worker type Glue version Estimated Cost*
10 m 7 s 32 DPUs G.1X 5 $2.34
11 m 50 s 10 DPUs G.1X 5 $0.88
19 m 7 s 4 DPUs G.1X 5 $0.59
8 m 19 s 20 DPUs G.2X 5 $1.32

*Estimated Cost = DPUs x Duration (hours) x $0.44 per DPU-hour (us-east-1)

Visualizing and analyzing geospatial data with Kepler.gl

Kepler.gl is an open-source geospatial analysis tool developed by Uber with code available at Github. Kepler.gl is designed for large-scale data exploration and visualization, offering multiple map layers, including point, arc, heatmap, and 3D hexagon. It supports various file formats like CSV, GeoJSON, and KML. In this use case, we will use Kepler.gl to present interactive visualizations that illustrate flight patterns, routes, and densities across global airspace.

Downloading the geospatial files

Before we can view the graph, we will need to download the flight files to our local machine, unzip them, and rename them (to make it easier to identify the files).

  1. Open your OS terminal command line.
  2. Create the folders to download the data processed in the steps before. In this case, we create kepler and kepler_csv.
    	#create kepler folders: first folder is to download the files,
    	#second folder is to organize the files to use in the next step
    	mkdir kepler
    	mkdir kepler_csv
    	
  3. Replace the bracketed variables with your account and directory information, then download all the CSV files.
    	#copy the files from Amazon S3 to local machine
    	aws s3 cp s3://blog-sedona-nessie-<account_number>-<aws_region>/visualization/ /<user_directory>/kepler --recursive
    	
  4. Extract the files, rename them, and move them to another folder.
    	# Extract the files processed by Spark and Sedona
    	gzip -d ./kepler/kepler_h3_density/*.gz
    	gzip -d ./kepler/kepler_track_points_sample/*.gz
    	
    	# Rename the Spark output files to more readable names
    	cd ./kepler/kepler_h3_density/
    	ls
    	mv part-00000-*.csv kepler_h3_density.csv
    	cd ..
    	
    	cd ./kepler/kepler_track_points_sample/
    	ls
    	mv part-00000-*.csv kepler_track_points_sample.csv
    	cd ..
    	
    	# Ensure the output folder exists
    	mkdir -p ../kepler_csv
    	
    	# Copy the renamed CSV files to the folder that will be used as input in kepler.gl
    	cp ./kepler/kepler_h3_density/*.csv ../kepler_csv
    	cp ./kepler/kepler_track_points_sample/*.csv ../kepler_csv
    	
  5. Your kepler_csv folder should look similar to the return of the command below.
    	#list the files in the kepler_csv directory
    	ls -l
    	total 11684
    	-rw-rw-r-- 1 ec2-user ec2-user 8630110 Jun 12 14:47 kepler_h3_density.csv
    	-rw-rw-r-- 1 ec2-user ec2-user 3331763 Jun 12 14:47 kepler_track_points_sample.csv
    	

Visualizing the data in a graph

Now that you have saved the data to your local machine, you can analyze the flight data through interactive map graphics. To import the data into the Kepler.gl web visualization tool:

  1. Open the Kepler.gl Demo web application.
  2. Load data into Kepler.gl:
    1. Choose Add Data in the left panel.
    2. Drag and drop both CSV files (flight_points and h3_density) into the upload area.
    3. Confirm that both datasets are loaded successfully.
  3. Delete all layers.
  4. Create the Flight Density Layer:
    1. Choose Add Layer in the left panel.
    2. In Basic, choose H3 as the layer type, then add the following configuration:
      1. Layer Name: Flight Density
      2. Data Source: kepler_h3_density.csv
      3. Hex ID: h3_index
    3. In the Fill Color section:
      1. Color: point_count
      2. Color Scale: Quantile.
      3. Color Range: Choose a blue/green gradient.
    4. Set Opacity to 0.7.
    5. In the Coverage section, set it to 0.9.
  5. Create the Flight Tracks Layer:
    1. Choose Add Layer in the left panel.
    2. In Basic, choose Point as the layer type, then add the following configuration:
      1. Layer Name: Flight Tracks
      2. Data Source: kepler_track_points_sample.csv
      3. Columns:
        1. Latitude: lat
        2. Longitude: lon
    3. In the Fill Color section:
      1. Solid Color: Orange
      2. Opacity: 0.3
    4. Set the Point’s Radius to 1
  6. The layers should look similar to the following figure.
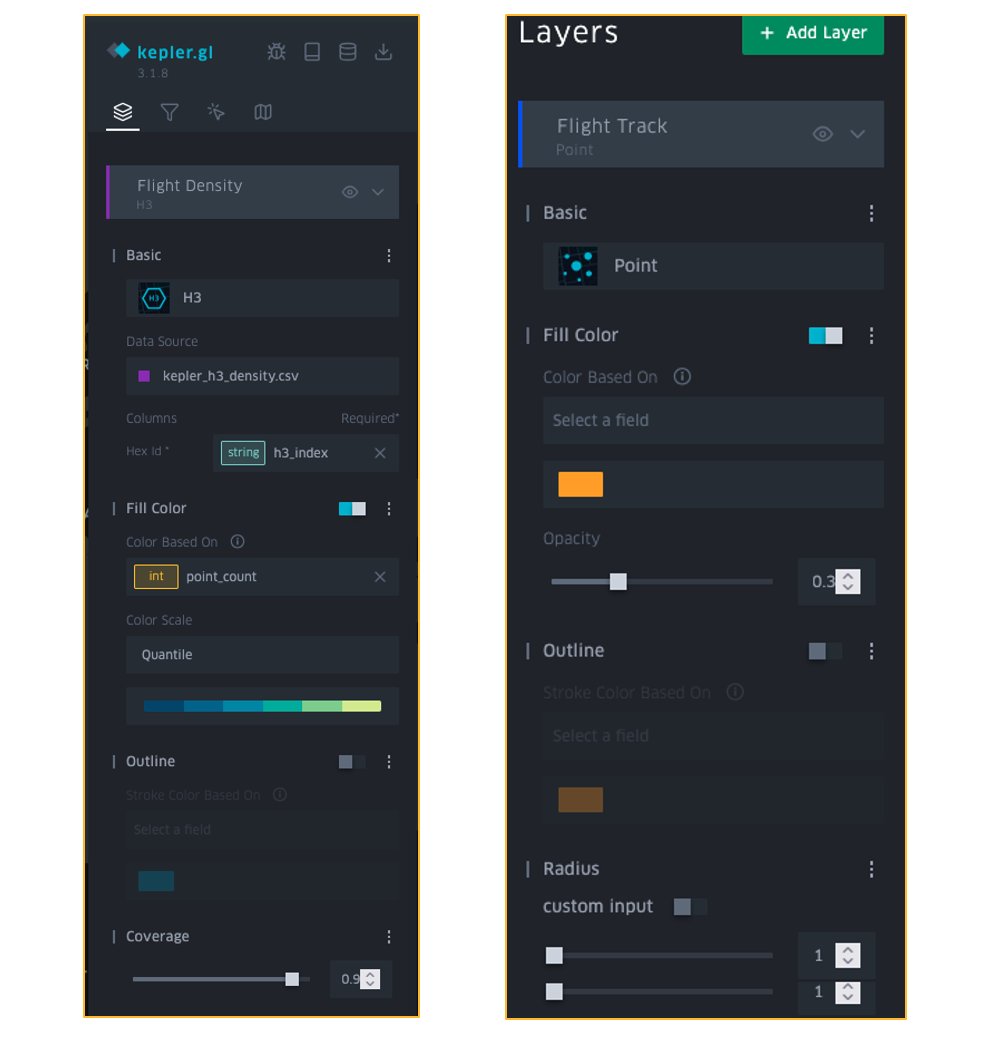
Kepler.gl layer configuration panel for Flight Density H3 layer using kepler_h3_density.csv data source.

  1. The graph visualization should now show flight density through color-coded hexagons, with individual flight tracks visible as orange points:
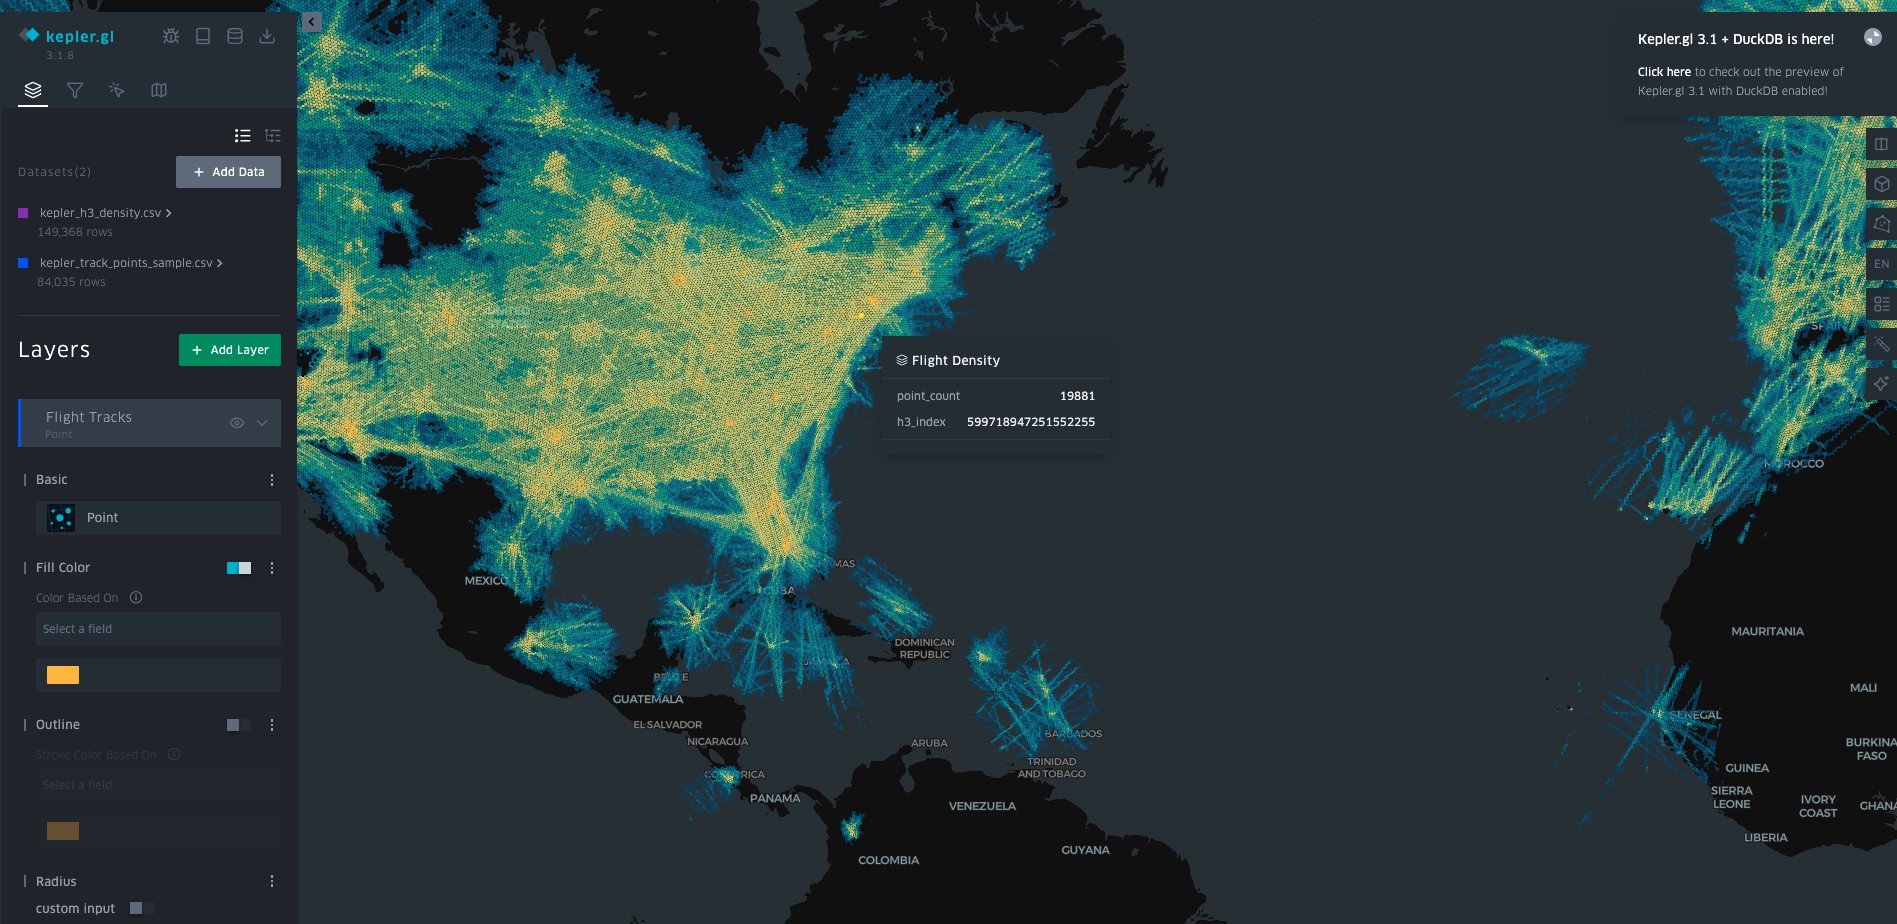
Kepler.gl interactive map visualization displaying global flight density heatmap. High-density areas shown in yellow over North America, particularly the United States.

There you go! Now that you have knowledge about geospatial data and have created your first use case, take the opportunity to do some analysis and learn some interesting facts about flight patterns.

It is possible to experiment with other interesting types of analysis in Kepler.gl, such as Time Playback.

Clean up

To clean up your resources, complete the following tasks:

  1. Delete the AWS Glue job process_sedona_geo_track.
  2. Delete content from the Amazon S3 buckets: blog-sedona-artifacts-<account_number>-<aws_region> and blog-sedona-nessie-<account_number>-<aws_region>.

Conclusion

In this post, we showed how processing geospatial data can present significant challenges due to its complex nature (from big data to data structure format). For this use case of flight trackers, it involves vast amounts of information across multiple dimensions such as time, location, altitude, and flight paths, however, the combination of Spark’s distributed computing capabilities and Sedona’s optimized geospatial functions helps overcome those challenges. The spatial partitioning and indexing features of Sedona, coupled with Spark’s framework, enable us to perform complex spatial joins and proximity analyses efficiently, simplifying the overall data processing workflow.

The serverless nature of AWS Glue eliminates the need for managing infrastructure while automatically scaling resources based on workload demands, making it an ideal platform for processing growing volumes of flight data. As the volume of flight data grows or as processing requirements fluctuate, with AWS Glue, you can quickly adjust resources to meet demand, ensuring optimal performance without the need for cluster management.

By converting the processed results into CSV format and visualizing them in Kepler.gl, it is possible to create interactive visualizations that reveal patterns in flight paths, and you can efficiently analyze air traffic patterns, routes, and other insights. This end-to-end solution demonstrates how a modern data strategy in AWS with the support of open-source tools can transform raw geospatial data into actionable insights.
About the authors

Ruan

Ruan Roloff is a Lead GTM Specialist Architect for Analytics and AI at AWS. During his time at AWS, he was responsible for the data journey and AI product strategy of customers across a range of industries, including finance, oil and gas, manufacturing, digital natives, public sector, and startups. He has helped these organizations achieve multi-million dollar use cases. Outside of work, Ruan likes to assemble and disassemble things, fish on the beach with friends, play SFII, and go hiking in the woods with his family.

Lucas

Lucas Vitoreti is a ProServe Data & Analytics Specialist at AWS with 12+ years in the data domain. Architects and delivers solutions for data warehouses, lakes, lakehouses, and meshes, helping organizations transform their data strategies and achieve business outcomes. Expertise in scalable data architectures and guiding data-driven transformations. He balances professional life with weightlifting, music, and family time.

Denys

Denys Gonzaga is a ProServe Consultant at AWS, he is an experienced professional with over 15 years of working across multiple technical domains, with a strong focus on development and data analytics. Throughout his career, he has successfully applied his skills in various industries, including aerospace, finance, telecommunications, and retail. Outside of AWS, Denys enjoys spending time with his family and playing video games.

Analyzing your data catalog: Query SageMaker Catalog metadata with SQL

Post Syndicated from Ramesh H Singh original https://aws.amazon.com/blogs/big-data/analyzing-your-data-catalog-query-sagemaker-catalog-metadata-with-sql/

As your data and machine learning (ML) assets grow, tracking which assets lack documentation or monitoring asset registration trends becomes challenging without custom reporting infrastructure. You need visibility into your catalog’s health, without the overhead of managing ETL jobs. The metadata feature of Amazon SageMaker provides this capability to users. Converting catalog asset metadata into Apache Iceberg tables stored in Amazon S3 Tables removes the need to build and maintain custom ETL pipelines. Your team can then query asset metadata directly using standard SQL tools. You can now answer governance questions like asset registration trends, classification status, and metadata completeness using standard SQL queries through tools like Amazon Athena, Amazon SageMaker Unified Studio notebooks, and BIsystems.

This automated approach reduces ETL development time and gives your team visibility into catalog health, compliance gaps, and asset lifecycle patterns. The exported tables include technical metadata, business metadata, project ownership details, and timestamps, partitioned by snapshot date to enable time travel queries and historical analysis. Teams can use this capability to proactively monitor catalog health, identify gaps in documentation, track asset lifecycle patterns, and make sure that governance policies are consistently applied.

How metadata export works

After you enable the metadata export feature, it runs automatically on a daily schedule:

  1. SageMaker Catalog creates the infrastructure — An Amazon Simple Storage Service (Amazon S3) table bucket named aws-sagemaker-catalog is created with an asset_metadata namespace and an empty asset table.
  2. Daily snapshots are captured — A scheduled job runs once per day around midnight (local time per AWS Region) to export updated asset metadata.
  3. Metadata is structured and partitioned — The export captures technical metadata (resource_id, resource_type), business metadata (asset_name, business_description), project ownership details, and timestamps, partitioned by snapshot_date for query performance.
  4. Data becomes queryable — Within 24 hours, the asset table appears in Amazon SageMaker Unified Studio under the aws-sagemaker-catalog bucket and becomes accessible through Amazon Athena, Studio notebooks, or external BI tools.
  5. Teams query using standard SQL — Data teams can now answer questions like “How many assets were registered last month?” or “Which assets lack business descriptions?” without building custom ETL pipelines.

The export evaluates catalog assets and their metadata properties in the domain, converting them into Apache Iceberg table format. The data flows into downstream analytics operations immediately, with no separate ETL or batch processes to maintain. The exported metadata becomes part of a queryable data lake that supports time-travel queries and historical analysis.

In this post, we demonstrate how to use the metadata export capability in Amazon SageMaker Catalog and perform analytics on these tables. We explore the following specific use-cases.

  • Audit historical changes to investigate what an asset looked like at a specific point in time.
  • Monitor asset growth view how the data catalog has grown over the last 30 days.
  • Track metadata improvements to see which assets gained descriptions or ownership over time.

Solution overview

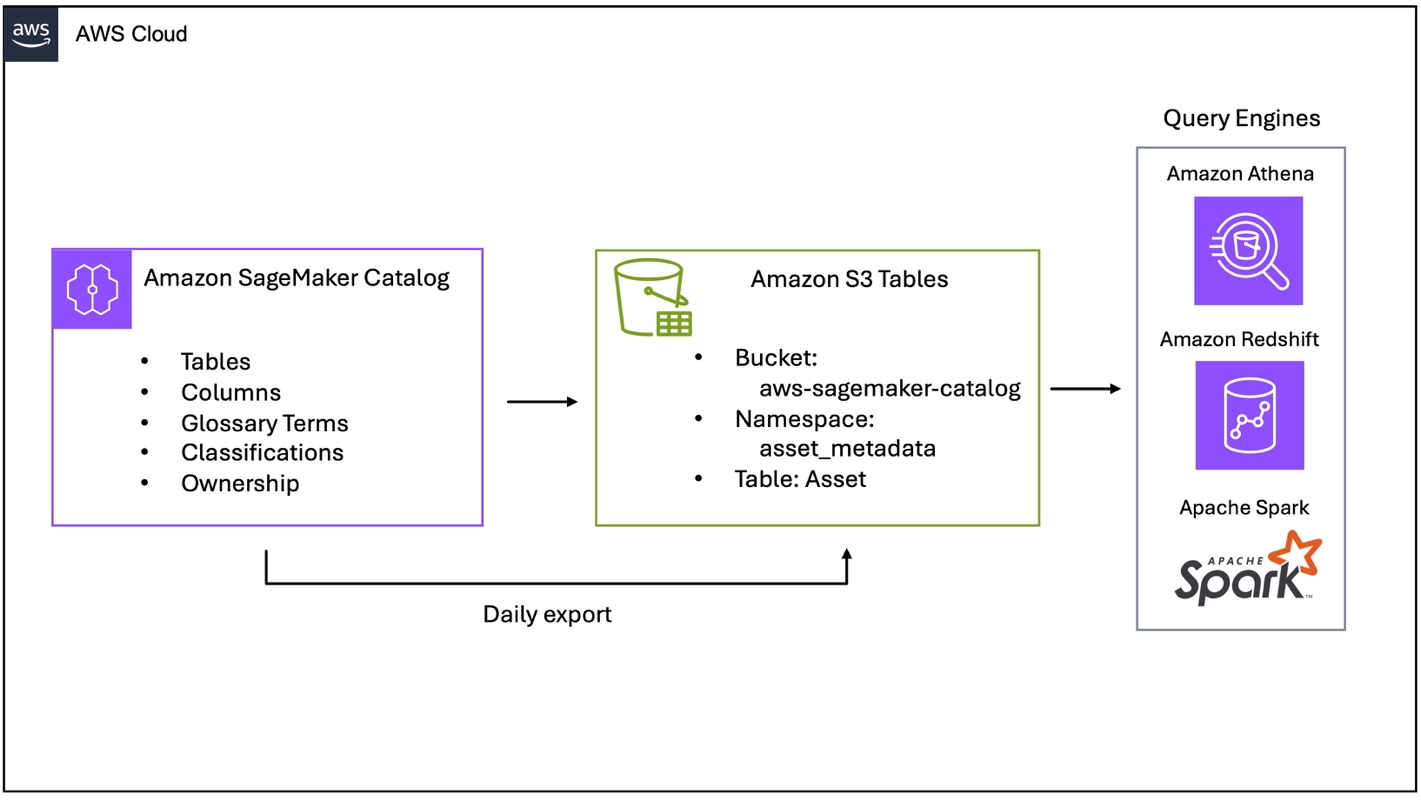
AWS Cloud architecture diagram showing data pipeline from Amazon SageMaker Catalog to Amazon S3 Tables with daily export, connecting to query engines including Amazon Athena, Amazon Redshift, and Apache Spark

Figure 1 – SageMaker catalog export to S3 Tables

The architecture consists of three key components:

  1. Amazon SageMaker Catalog exports asset metadata daily to Amazon S3.
  2. S3 Tables stores metadata as Apache Iceberg tables in the aws-sagemaker-catalog bucket with ACID compliance and time travel.
  3. Query engines (Amazon Athena, Amazon Redshift, and Apache Spark) access metadata using standard SQL from the asset_metadata.asset table.

What metadata is exposed?

SageMaker Catalog exports metadata in the asset_metadata.asset table:

Metadata Type Fields Description
Technical metadata resource_id, resource_type_enum, account_id, region Resource identifiers (ARN), types (GlueTable, RedshiftTable, S3Collection), and location
Namespace hierarchy catalog, namespace, resource_name Organizational structure for assets
Business metadata asset_name, business_description Human-readable names and descriptions
Ownership extended_metadata['owningEntityId'] Asset ownership information
Timestamps asset_created_time, asset_updated_time, snapshot_time Creation
Custom metadata extended_metadata['form-name.field-name'] User-defined metadata forms as key-value pairs

The snapshot_time column supports point-in-time analysis and query of historical catalog states.

Prerequisites

To follow along with this post, you must have the following:

For SageMaker Unified Studio domain setup instructions, refer to the SageMaker Unified Studio Getting started guide.

After you complete the prerequisites, complete the following steps.

  1. Add this policy to our IAM user or role to enable metadata export. If using SageMaker Unified Studio to query the catalog, add this policy to the AmazonSageMakerAdminIAMExecutionRole managed role.
{ "Version": "2012-10-17", 
"Statement": [ 
{
 "Effect": "Allow",
 "Action": [ "datazone:GetDataExportConfiguration",
 "datazone:PutDataExportConfiguration"
 ],
 "Resource": "*"
 },
 {
 "Effect": "Allow",
 "Action": [
 "s3tables:CreateTableBucket",
 "s3tables:PutTableBucketPolicy"
 ],
 "Resource": "arn:aws:s3tables:*:*:bucket/aws-sagemaker-catalog" 
} 
]
}
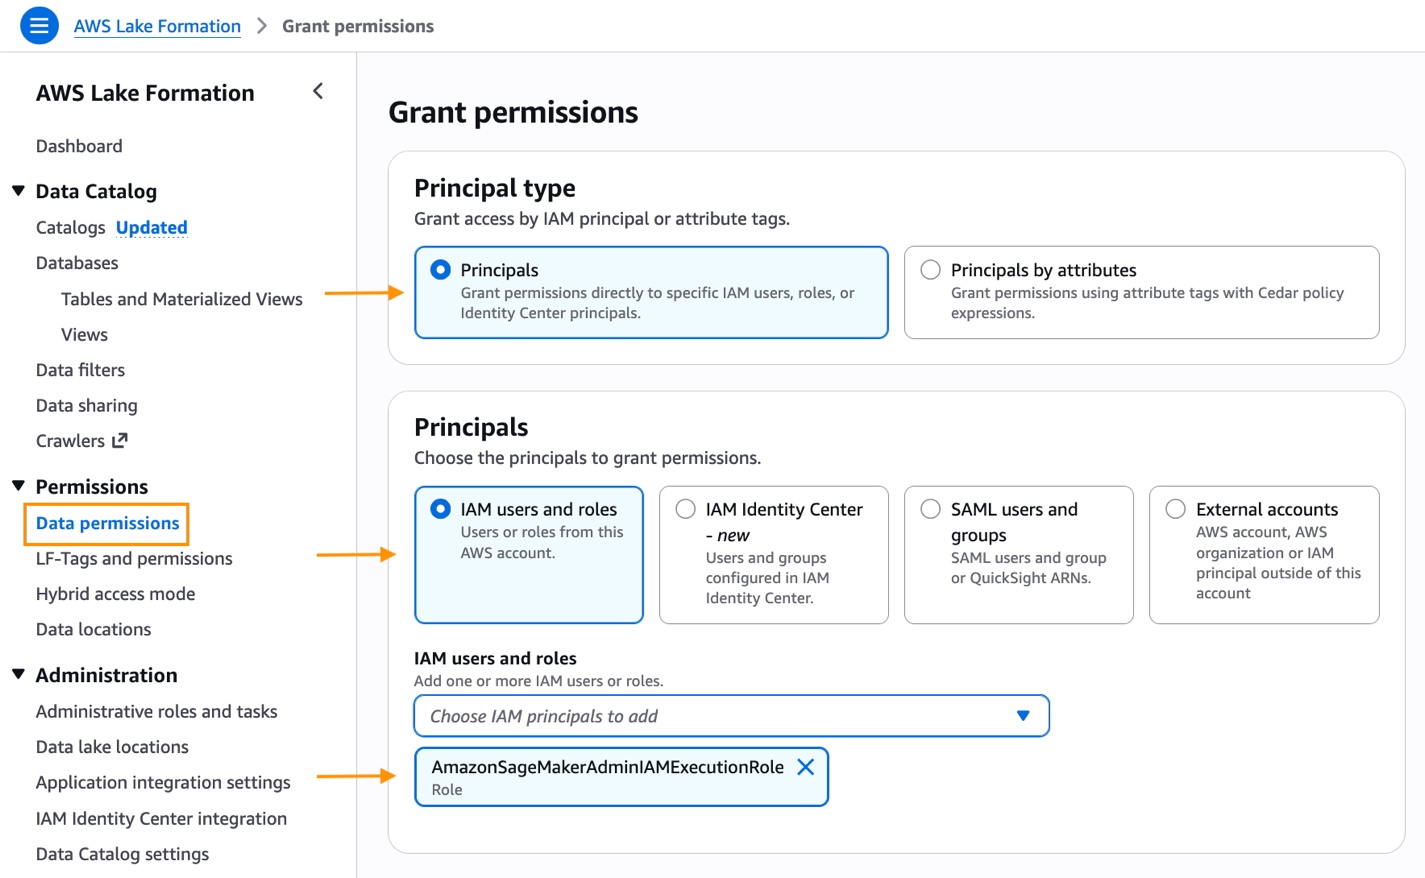
  1. Grant describe and select permissions for SageMaker Catalog with AWS Lake Formation. This step can be performed in the AWS Lake Formation console.
    1. Select Permissions -> Data permissions and choose Grant.

      AWS Lake Formation Grant Permissions interface showing principal type selection with IAM users and roles option selected and AmazonSageMakerAdminIAMExecutionRole assigned

      Figure 2 – AWS Lake Formation grant permission

    2. Under Principal type, select Principals, IAM users and roles and the AWS managed AmazonSageMakerAdminIAMExecutionRole execution role.
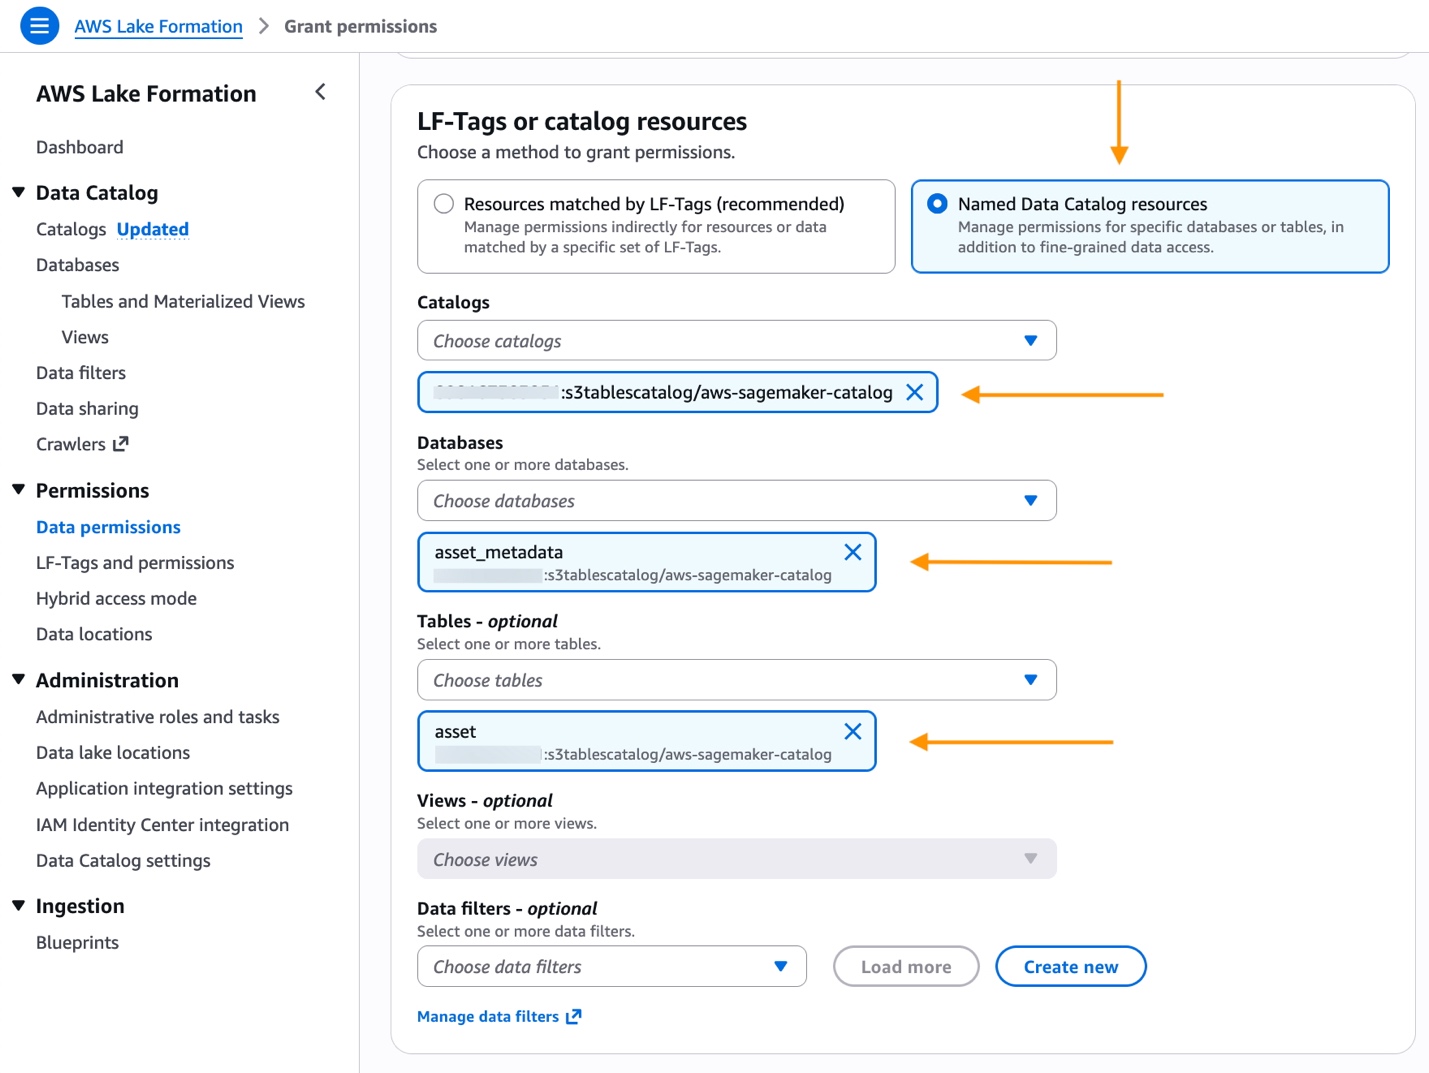
    3. Choose Named Data Catalog resources.
    4. Under Catalogs, search for and select <account-id>:s3tablecatalog/aws-sagemaker-catalog.
    5. Under Databases, select asset_metadata database.
      AWS Lake Formation Grant Permissions page showing Named Data Catalog resources method with s3tablescatalog/aws-sagemaker-catalog selected, asset_metadata database, and asset table configured

      Figure 3 – AWS Lake Formation catalog, database, and table

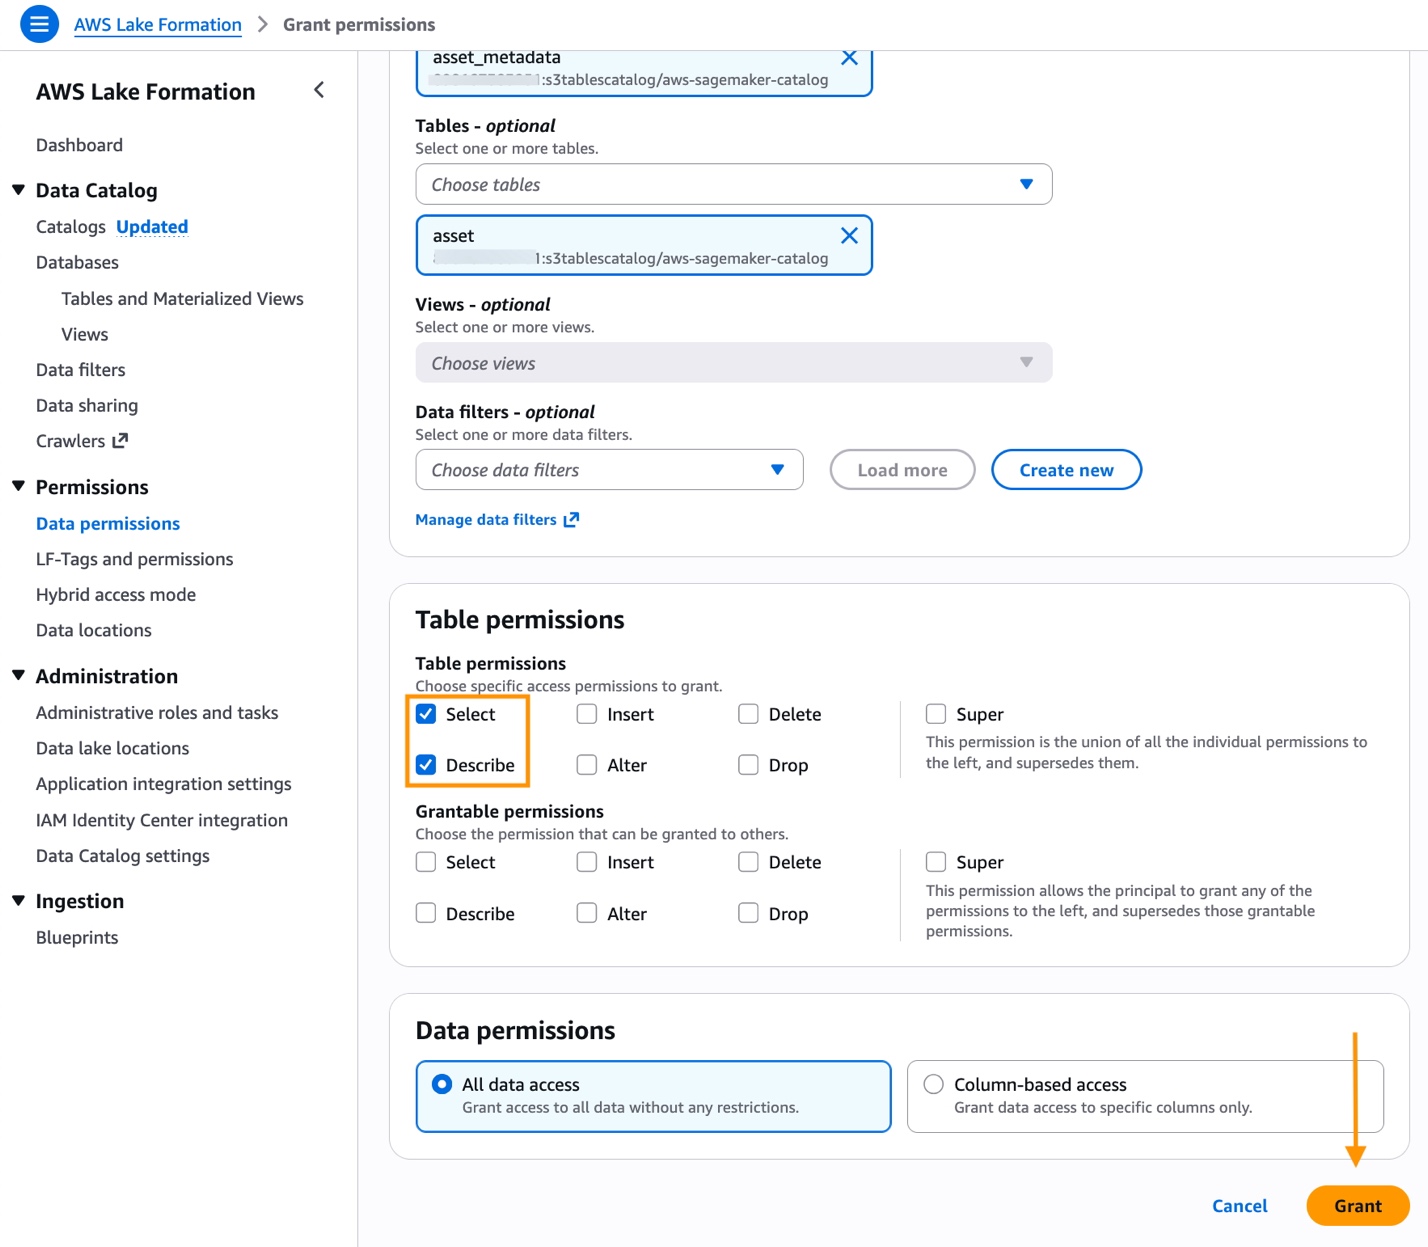
      AWS Lake Formation Grant Permissions interface showing table permissions with Select and Describe checked, grantable permissions section, and All data access radio button selected

      Figure 4 – AWS Lake Formation grant permission

    6. For Table, select asset.
    7. Under Table permissions, check Select and Describe.
    8. Choose Grant to save the permissions.

Enable data export using the AWS CLI

Configure metadata export using the PutDataExportConfiguration API. The Amazon DataZone service automatically creates an S3 table bucket named aws-sagemaker-catalog with an asset_metadata namespace, and schedules a daily export job. Asset metadata is exported once daily around midnight local time per AWS Region.

The SageMaker Domain identifier is available on domain detail page in the AWS Management Console. Accessing the asset table through the S3 Tables console or the Data tab in SageMaker Unified Studio can require up to 24 hours.

AWS CLI command to enable SageMaker catalog export:

aws datazone put-data-export-configuration --domain-identifier <domain-id> --region <region> --enable-export

Use this AWS CLI command to validate the configuration is enabled:

aws datazone get-data-export-configuration --domain-identifier <domain-id> --region <region>
{
    "isExportEnabled": true,
    "status": "COMPLETED",
    "s3TableBucketArn": "arn:aws:s3tables:<region>:<account-id>:bucket/aws-sagemaker-catalog",
    "createdAt": "2025-11-26T18:24:02.150000+00:00",
    "updatedAt": "2026-02-23T19:33:40.987000+00:00"
}

Access the exported asset table

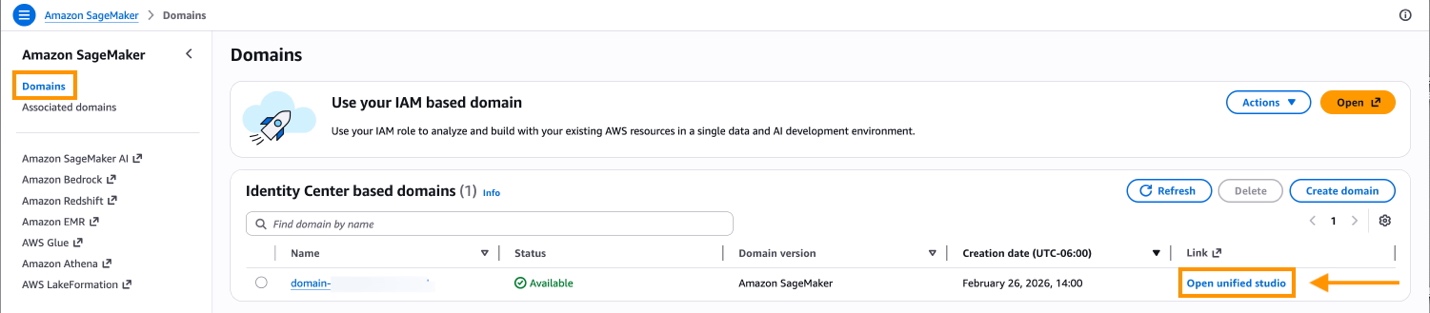
  1. Navigate to Amazon SageMaker Domains in the AWS Management Console.
  2. Select your domain and select Open.

    Amazon SageMaker Domains management page showing an Identity Center based domain with Available status, created February 26, 2026, with Open unified studio button highlighted

    Figure 5 – Open Amazon SageMaker Unified Studio

  3. In SageMaker Unified Studio, choose a project from the Select a project dropdown list.
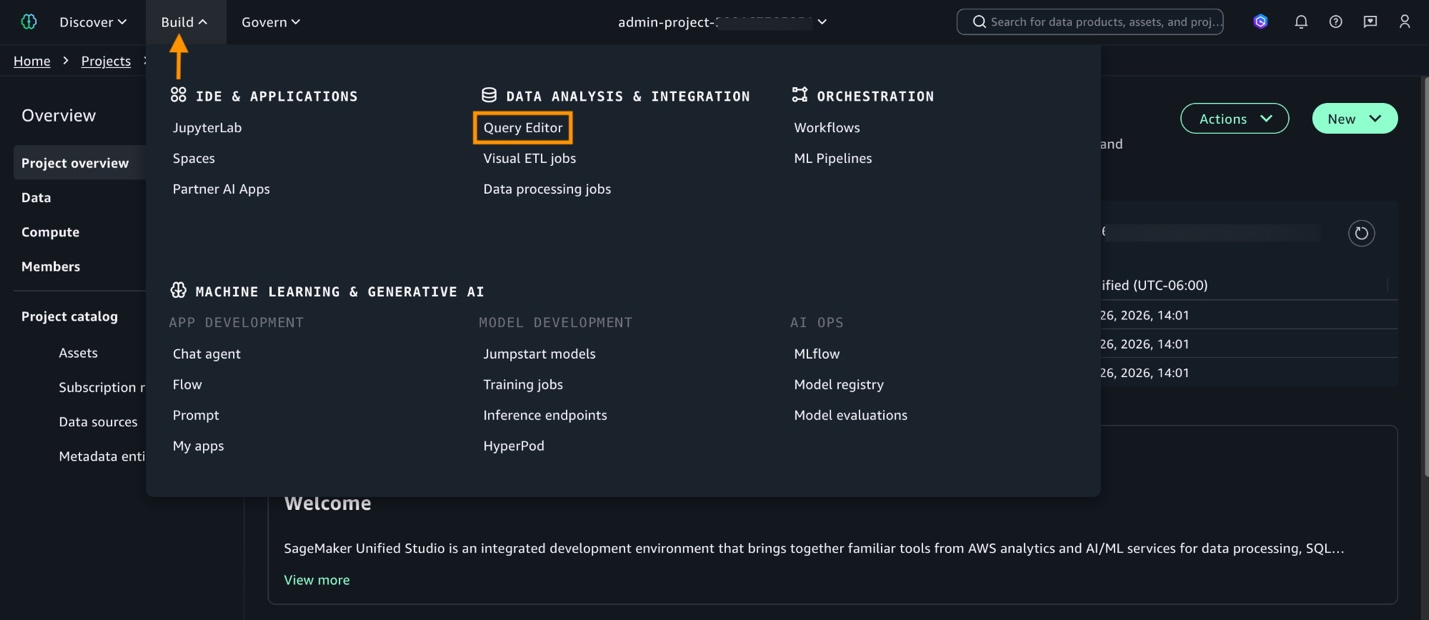
  4. To query SageMaker catalog data, select Build in the menu bar and then choose Query Editor. To create a new project, follow the instructions in the Amazon SageMaker Unified Studio User Guide.

    SageMaker Unified Studio project overview dashboard showing IDE and Applications, Data Analysis and Integration with Query Editor highlighted, Orchestration, and Machine Learning and Generative AI categories

    Figure 6 – Open SageMaker Unified Studio Query Editor

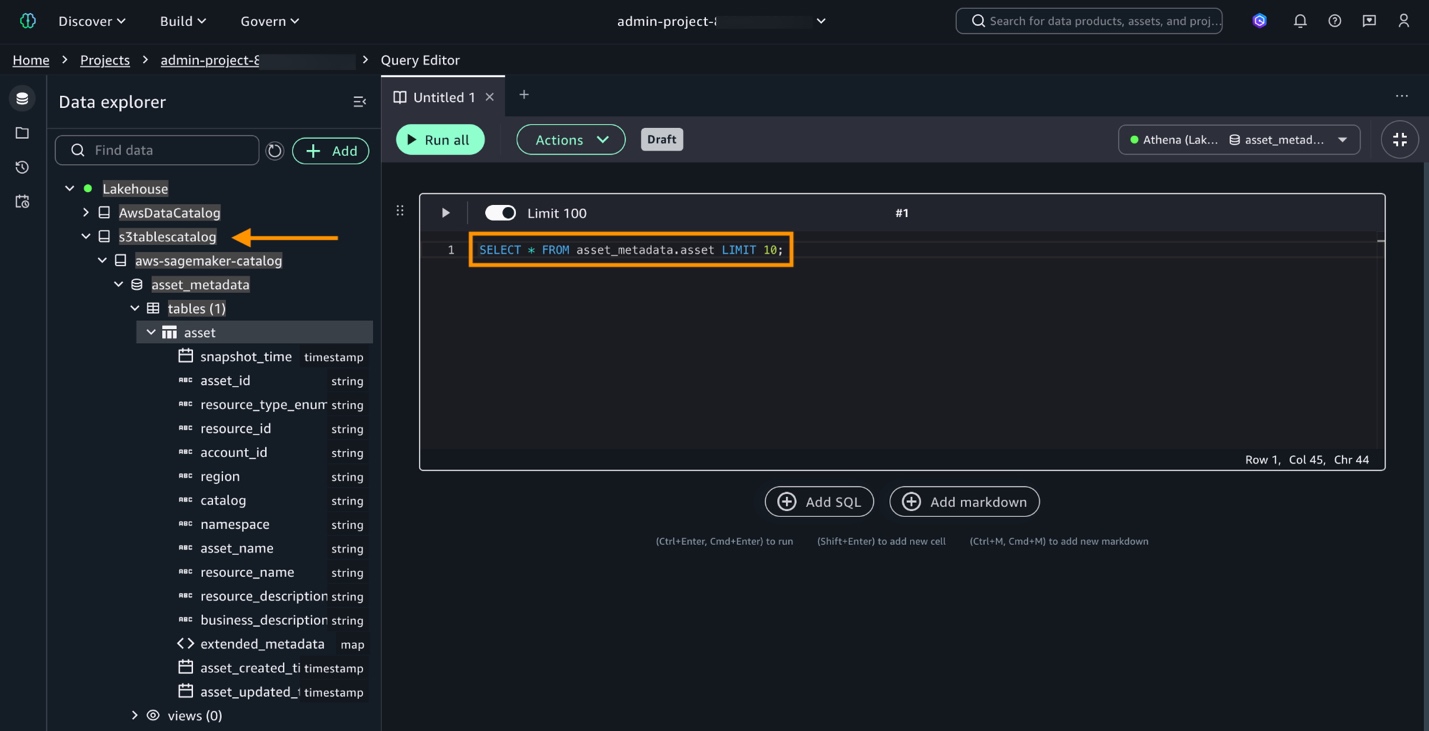
The asset_metadata.asset table is available in Data explorer. Use Data explorer to view the schema and query data to perform analytics from.

  1. Expand Catalogs in Data explorer. Then, select and expand s3tablecatalog, aws-sagemaker-catalog, asset_metadata, and asset.
  2. Test querying the catalog with SELECT * FROM asset_metadata.asset LIMIT 10;.
SageMaker Unified Studio Query Editor with Data Explorer showing Lakehouse hierarchy including s3tablescatalog, aws-sagemaker-catalog, asset_metadata database, and asset table schema with SQL SELECT query

Figure 7 – Query SageMaker catalog

Queries for observability and analytics

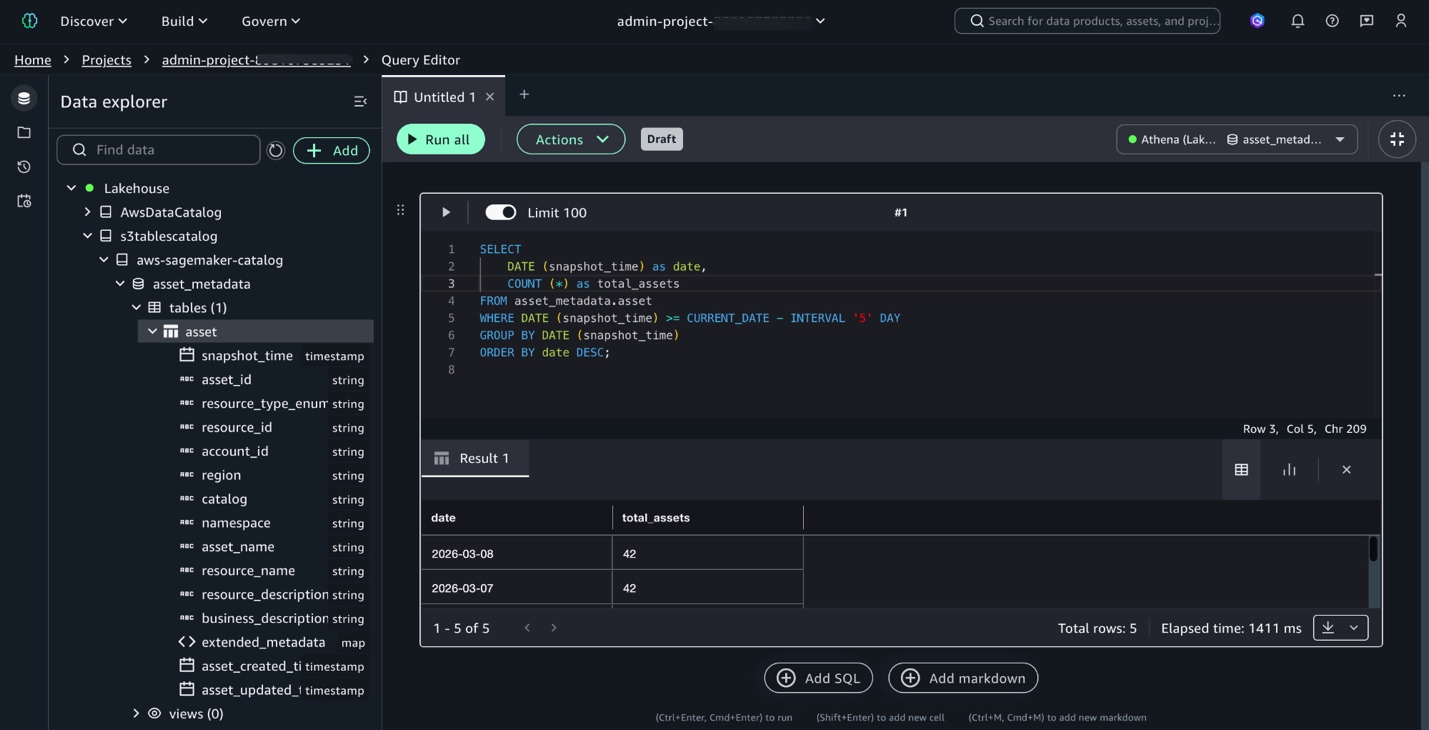
With setup complete, execute queries to gain insights on catalog usage and changes. To monitor asset growth, and view how the data catalog has grown over the last five days:

SELECT 
    DATE (snapshot_time) as date,
    COUNT (*) as total_assets
FROM asset_metadata.asset
WHERE 
     DATE (snapshot_time) >= CURRENT_DATE - INTERVAL '5' DAY
GROUP BY DATE (snapshot_time)
ORDER BY date DESC;
SageMaker Unified Studio Query Editor showing SQL aggregation query on asset_metadata.asset table with results displaying date and total_assets columns, returning 42 assets for March 7-8, 2026"

Figure 8 – Query asset growth

Use the catalog to track metadata changes to determine which assets gained descriptions or ownership over time. Use this query to identify assets that gained business descriptions over the past five days by comparing today’s snapshot with the earlier snapshot.

SELECT
    t.asset_id,
    t.resource_name,
    p.business_description as description_before,
    t.business_description as description_now
FROM asset_metadata.asset t
JOIN asset_metadata.asset p ON t.asset_id = p.asset_id
WHERE DATE(t.snapshot_time) = CURRENT_DATE
    AND DATE(p.snapshot_time) = CURRENT_DATE - INTERVAL '5' DAY
    AND p.business_description IS NULL
    AND t.business_description IS NOT NULL;

Investigate asset values at a specific point in time using this query to retrieve metadata from any snapshot date.

SELECT
     asset_id,
     resource_name,
     business_description,
     extended_metadata['owningEntityId'] as owner,
     snapshot_time
FROM asset_metadata.asset
WHERE asset_id = 'your-asset-id'
     AND DATE(snapshot_time) = DATE('2025-11-26');

Clean up resources

To avoid ongoing charges, clean up the resources created in this walkthrough:

  1. Disable metadata export:

Disable the daily metadata export to stop new snapshots:

aws datazone put-data-export-configuration \
  --domain-identifier <domain-id. \
  --no-enable-export \
  --region <region>
  1. Delete S3 Tables resources:

Optionally, delete the S3 Tables namespace containing the exported metadata to remove historical snapshots and stop storage charges. For instructions on how to delete S3 tables, see Deleting an Amazon S3 table in the Amazon Simple Storage Service User Guide.

Conclusion

In this post, you enabled the metadata export feature of SageMaker Catalog and used SQL queries to gain visibility into your asset inventory. The feature converts asset metadata into Apache Iceberg tables partitioned by snapshot date, so you can perform time-travel queries, monitor catalog growth, track metadata completeness, and audit historical asset states. This provides a repeatable, low-overhead way to maintain catalog health and meet governance requirements over time.

To learn more about Amazon SageMaker Catalog, see the Amazon SageMaker Catalog documentation. To explore Apache Iceberg table formats and time-travel queries, see the Amazon S3 Tables documentation.


About the Authors

Photo of Author Ramesh Singh

Ramesh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon SageMaker team. He is passionate about building high-performance ML/AI and analytics products that help enterprise customers achieve their critical goals using cutting-edge technology.

Photo of Author Pradeep Misra

Pradeep is a Principal Analytics and Applied AI Solutions Architect at AWS. He is passionate about solving customer challenges using data, analytics, and Applied AI. Outside of work, he likes exploring new places and playing badminton with his family. He also likes doing science experiments, building LEGOs, and watching anime with his daughters.

Photo of Author - Rohith Kayathi

Rohith is a Senior Software Engineer at Amazon Web Services (AWS) working with Amazon SageMaker team. He leads business data catalog, generative AI–powered metadata curation, and lineage solutions. He is passionate about building large-scale distributed systems, solving complex problems, and setting the bar for engineering excellence for his team.

Photo of AUthor - Steve Phillips

Steve is a Principal Technical Account Manager and Analytics specialist at AWS in the North America region. Steve currently focuses on data warehouse architectural design, data lakes, data ingestion pipelines, and cloud distributed architectures.

Configure a custom domain name for your Amazon MSK cluster enabled with IAM authentication

Post Syndicated from Mazrim Mehrtens original https://aws.amazon.com/blogs/big-data/configure-a-custom-domain-name-for-your-amazon-msk-cluster-enabled-with-iam-authentication/

Most Amazon Managed Streaming for Apache Kafka (Amazon MSK) customers are simplifying and standardizing access control to Kafka resources using AWS Identity and Access Management (IAM) authentication. This adoption is also accelerated as Amazon MSK now supports IAM authentication in popular languages including Java, Python, Go, JavaScript, and .NET.

In the first part of Configure a custom domain name for your Amazon MSK cluster, we discussed about why custom domain names are important and provided details on how to configure a custom domain name in Amazon MSK when using SASL_SCRAM authentication. In this post, we discuss how to configure a custom domain name in Amazon MSK when using IAM authentication. We recommend you read the first part of this blog as it captures solution details implementation steps.

Solution overview

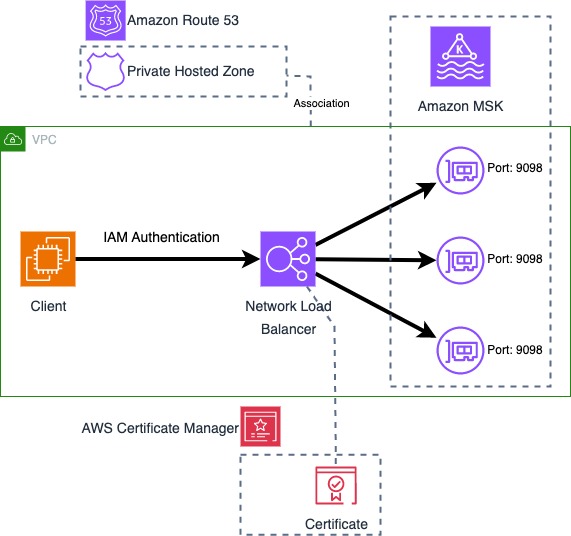
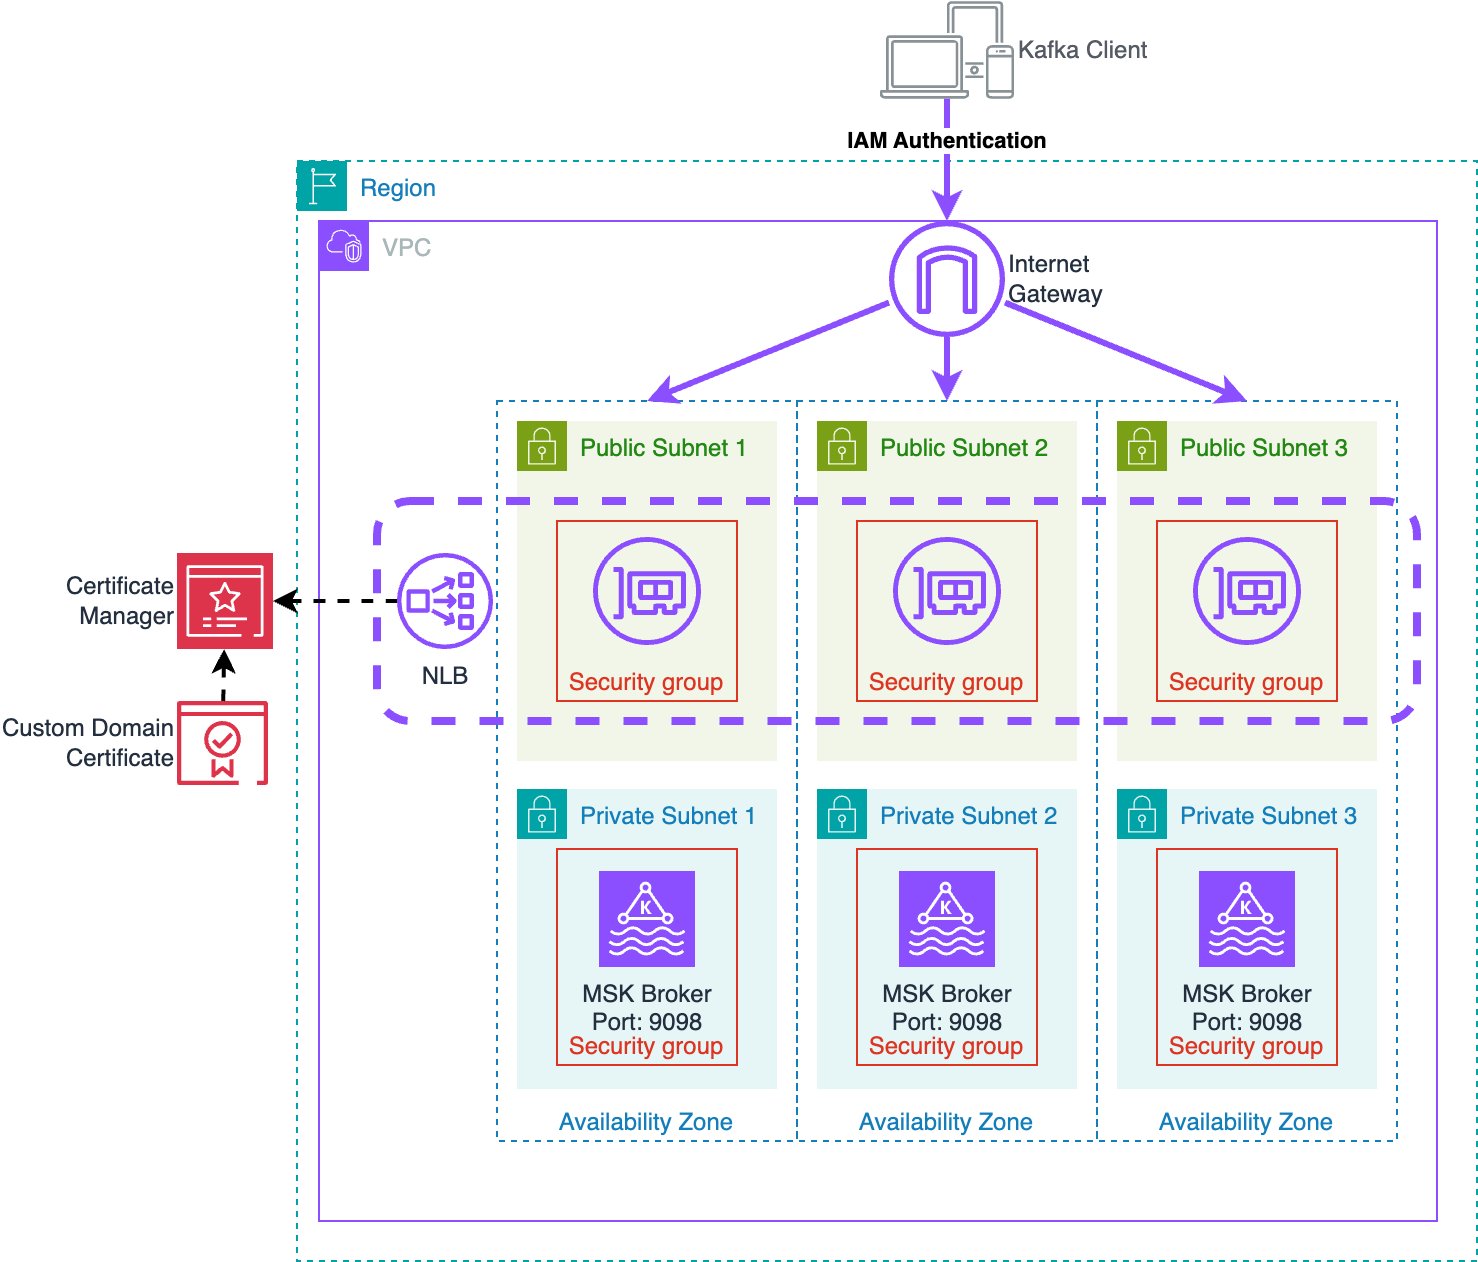
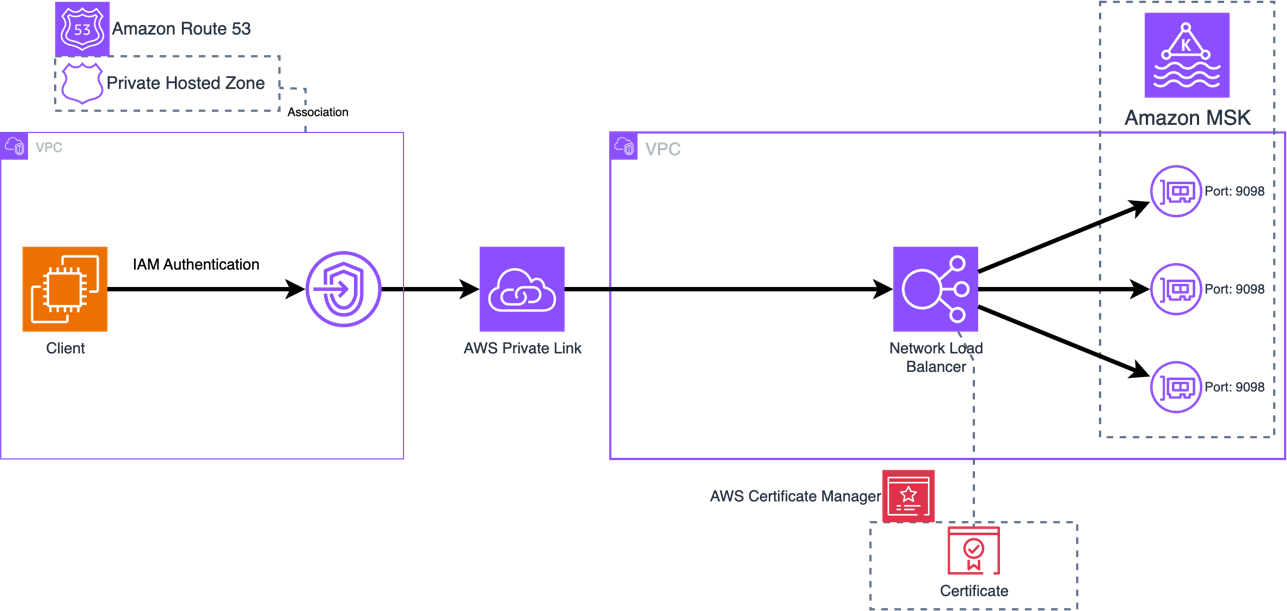
IAM authentication for Amazon MSK uses TLS to encrypt the Kafka protocol traffic between the client and Kafka broker. To use a custom domain name, the Kafka broker needs to present a server certificate that matches the custom domain name. To achieve this, this solution uses an Network Load Balancers (NLBs) with Amazon Certificate Manager to provide a custom certificate on behalf of the MSK brokers, and a Route 53 Private Hosted Zone to provide DNS for the custom domain name.

The following diagram shows all components used by the solution.

Architecture showing configuration of custom domain name with Amazon MSK

Certificate management

For clients to perform TLS communication with the MSK cluster the cluster needs to provide a certificate with hostnames matching the custom domain name. This solution uses a certificate in AWS Certificate Manager (ACM) signed with a Private Certificate Authority (PCA) for TLS with the custom domain name. This solution uses a certificate with bootstrap.example.com as the Common Name (CN) so that the certificate is valid for the bootstrap address, and Subject Alternative Names (SANs) are set for all broker DNS names (such as b-1.example.com). Since this solution uses a private certificate authority, the CA chain must be imported into the client trust stores.

This solution works with any server certificate, whether certificates are signed by a public or private Certificate Authority (CA). You can import existing certificates into ACM to be used with this solution. Certificates must provide a common name and/or subject alternative names that match the bootstrap DNS address as well as the individual broker DNS addresses. If the certificate is issued by a private CA, clients need to import the root and intermediate CA certificates to the client trust store. If the certificate is issued by a public CA, the root and intermediate CA certificates will be in the default trust store.

Network Load Balancer

The NLB provides the ability to use a TLS listener. The ACM certificate is associated with the listeners and enables TLS negotiation between the client and the NLB. The NLB performs a separate TLS negotiation between itself and the MSK brokers. In addition to the above architecture, this solution also allows using AWS Private Link to connect the cluster to external VPCs. This allows secure access to MSK between VPCs while using a custom domain name.

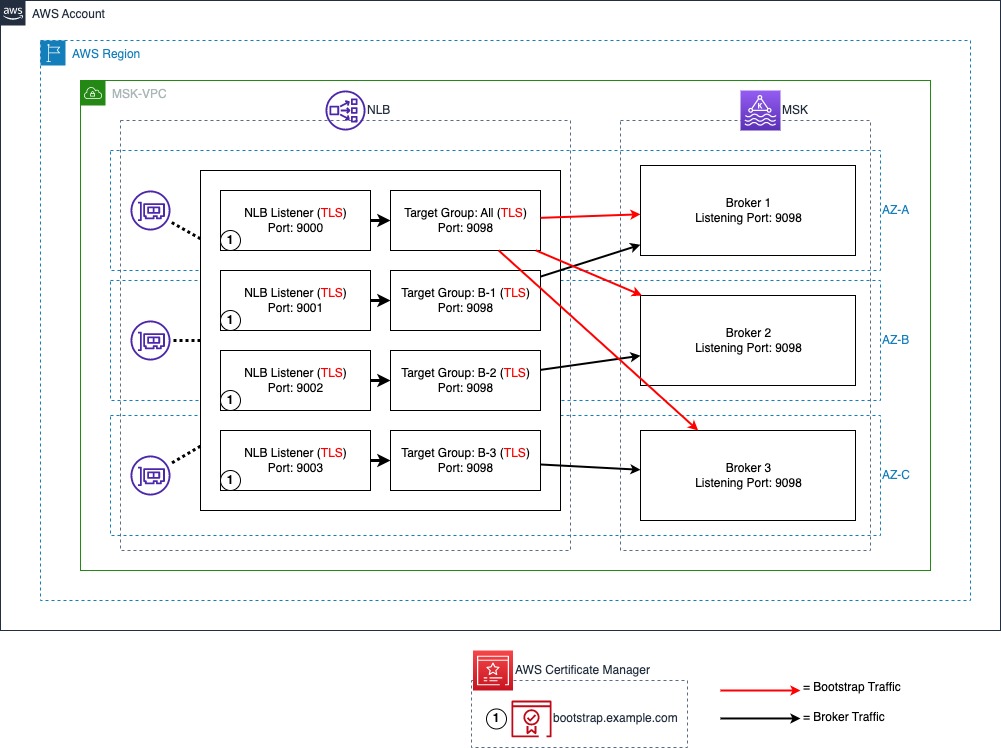
The following diagram illustrates the NLB port and target configuration. A TLS listener with port 9000 is used for bootstrap connections with all MSK brokers set as targets. IAM authentication is configured to run on port 9098 of the MSK brokers using a TLS target type. A TLS listener port is used to represent each broker in the MSK cluster. In this post, there are three brokers in the MSK cluster starting with port 9001, representing broker 1 and up to port 9003, representing broker 3.

Target Group mapping in NLB

Domain Name System (DNS)

For the client to resolve DNS queries for the custom domain, we use an Amazon Route 53 private hosted zone to host the DNS records, and associate it with the client’s VPC to enable DNS resolution from the Route 53 VPC resolver. This solution uses a private MSK cluster and private DNS. For publicly accessible MSK clusters a public NLB and DNS provider such as a Route53 public hosted zone can be used.

Amazon MSK

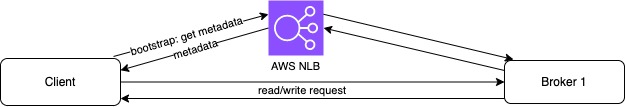
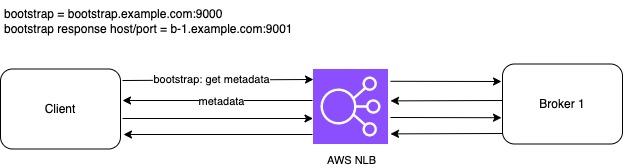
Finally, each broker needs to have its advertised listeners configuration (advertised.listeners) updated to match the custom domain name and NLB ports. Advertised listeners is a configuration option used by Kafka clients to connect to the brokers. By default, an advertised listener is not set. Once set, Kafka clients use the advertised listener instead of listeners to obtain the connection information for brokers. MSK brokers use the listener configuration to tell clients the DNS names and ports to use to connect to the individual brokers for each authentication type enabled. Advertised listeners are unique to each broker; and the cluster won’t start if multiple brokers have the same advertised listener address. For this reason, this solution uses a unique custom DNS name for each broker (such as, b-1.example.com).

Solution Deployment

To deploy the solution, use the CloudFormation template from the GitHub repository.

This template deploys a VPC, NLB, PCA, ACM certificate, MSK cluster, and an Amazon EC2 instance for cluster connectivity. The EC2 instance includes a script to handle updating the broker advertised.listeners settings to match the custom domain name. For more information on deploying a CloudFormation template, refer to Create a stack from the CloudFormation console.

After deploying the CloudFormation template, run the script to update advertised listeners as follows:

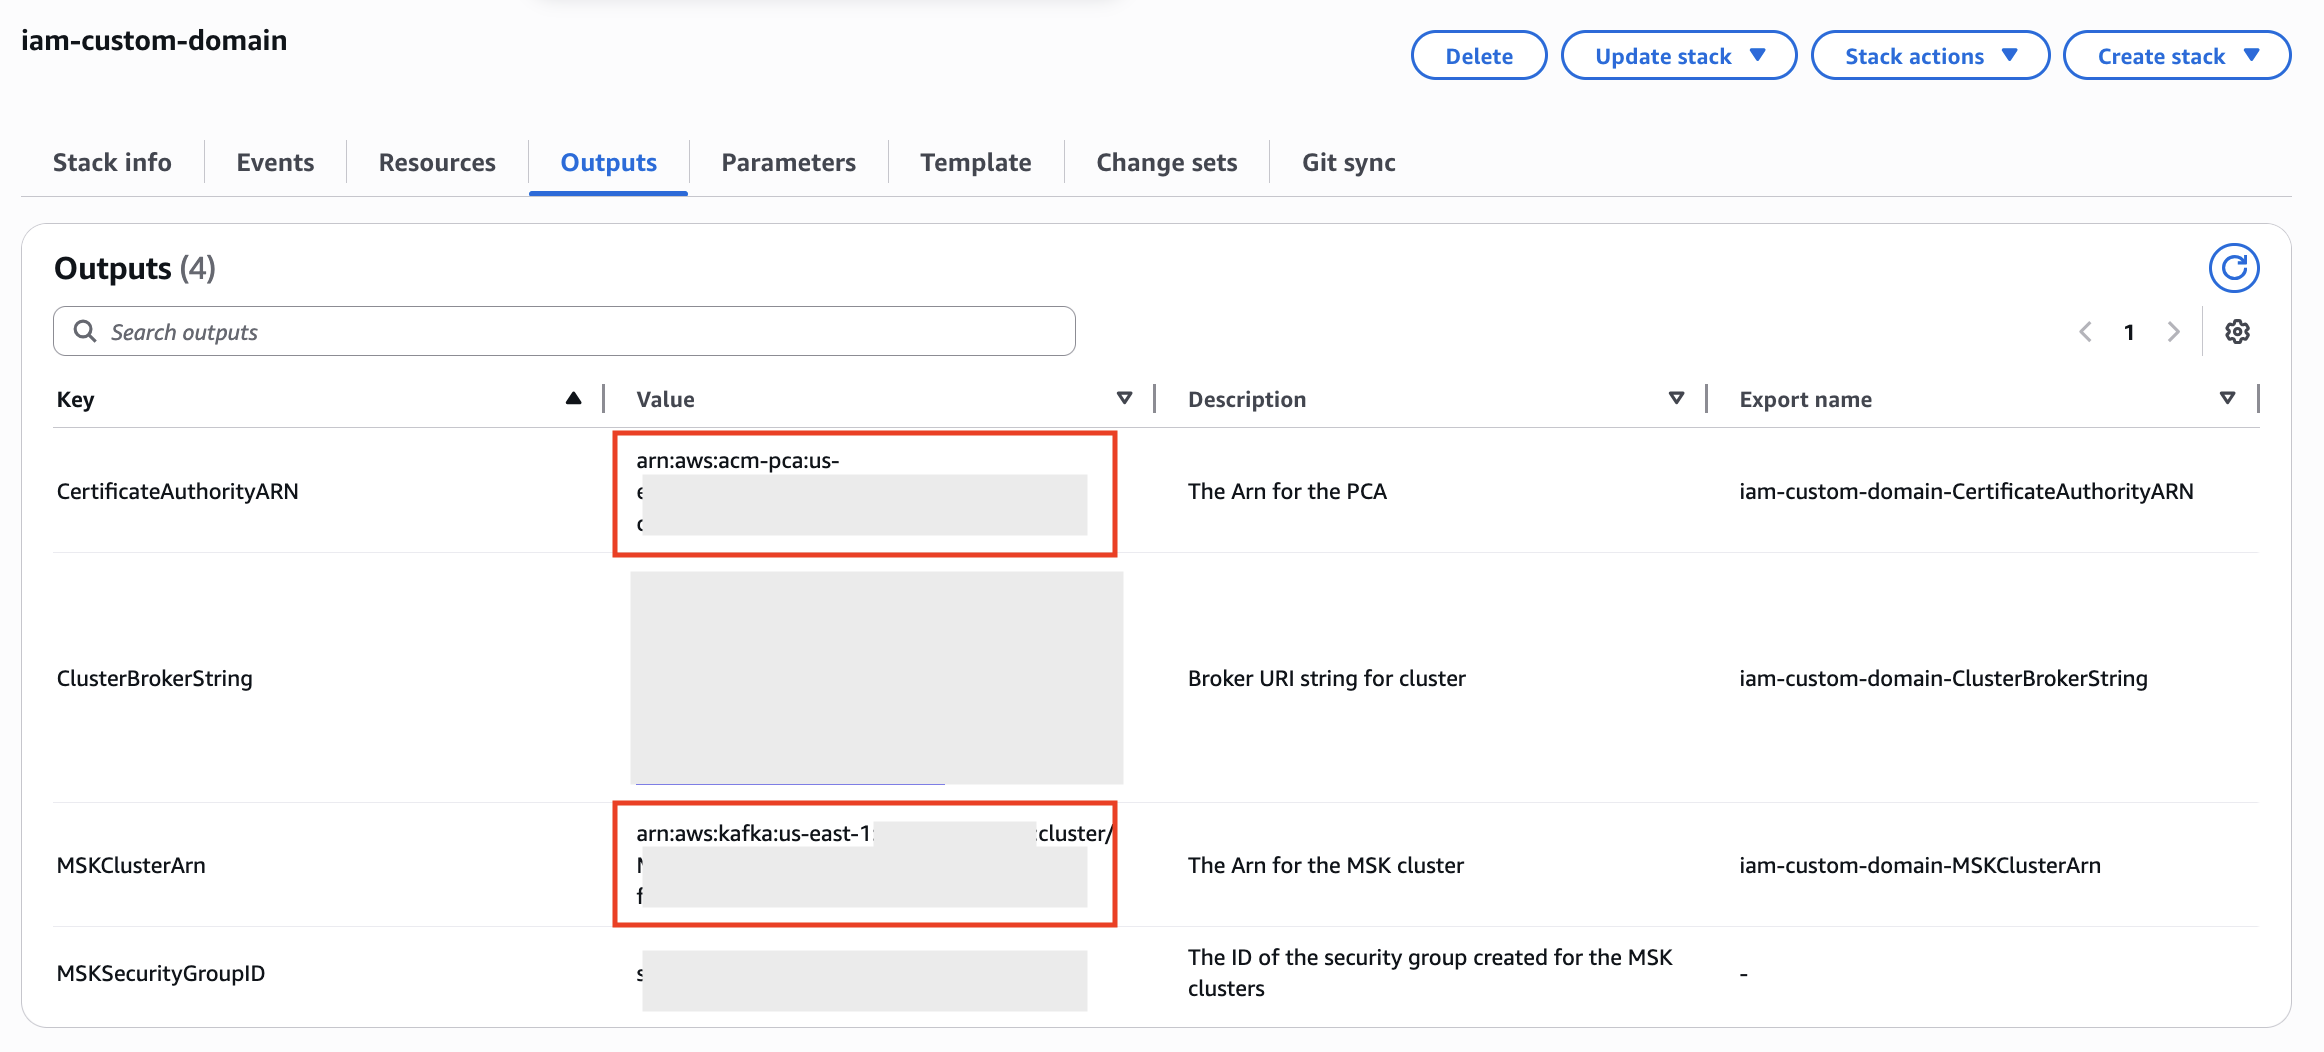
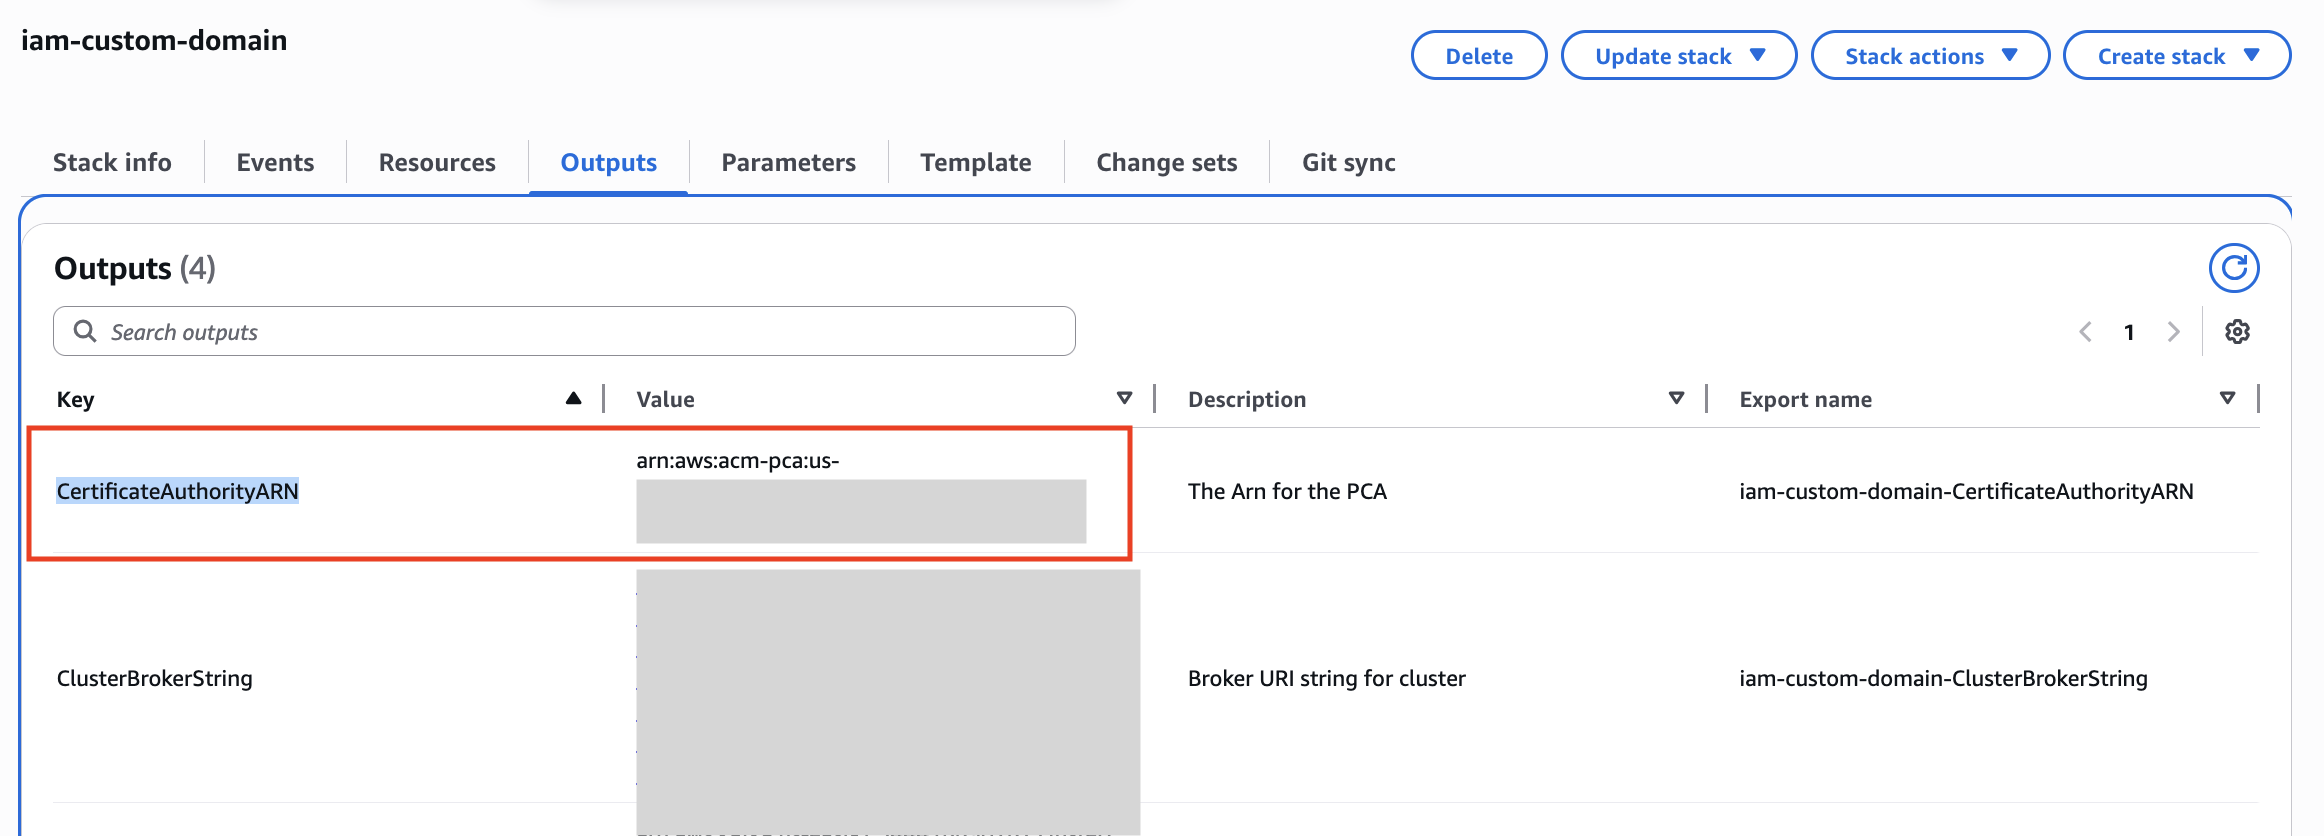
  1. Retrieve the MSKClusterARN and CertificateAuthorityARN from the CloudFormation outputs for your stack as they will be used in subsequent steps.
  2. Navigate to the EC2 console and identify the KafkaClientInstance. Choose Connect to connect to the instance using AWS Systems Manager Session Manager.
  3. Session Manager starts a session in shell. Start a bash session with the command:
    bash -l

  4. The Kafka client SDKs have already been installed in the EC2 instance. You can update the advertised.listeners configuration as follows, replacing CLUSTER_ARN with the ARN of your MSK cluster retrieved from CloudFormation in step 1:
    ./update_advertised_listeners.sh --region us-east-1 --cluster-arn CLUSTER_ARN

    Note that once this script completes, the brokers will have new advertised listeners configurations. Connections using the standard IAM address for the MSK service will not work until we complete the next steps, as the brokers will redirect connections over this address back to the custom domain name and TLS will fail.

  5. Next, we need to create a truststore with the certificate for our AWS Private Certificate Authority (PCA) to allow TLS with the NLB. In the following command, replace PCA_ARN with the ARN of the PCA retrieved from CloudFormation in step 1:
    We’re using the default Java truststore which uses the password changeit.When asked “Trust this certificate?” enter “yes”.
    export PCA_ARN=<<PCA_ARN>>
    export REGION=<<REGION>>
    
    cp /etc/pki/java/cacerts . && chmod 600 cacerts
    aws acm-pca get-certificate-authority-certificate --certificate-authority-arn $PCA_ARN --region $REGION | jq -r '.Certificate' > pca.pem
    keytool -import -file pca.pem -alias AWSPCA -keystore cacerts

  6. Create a new properties file to allow IAM authentication with our custom truststore:
    cat <<EOF >> /home/ssm-user/client-iam.properties
    ssl.truststore.location=/home/ssm-user/cacerts
    ssl.truststore.password=changeit
    EOF

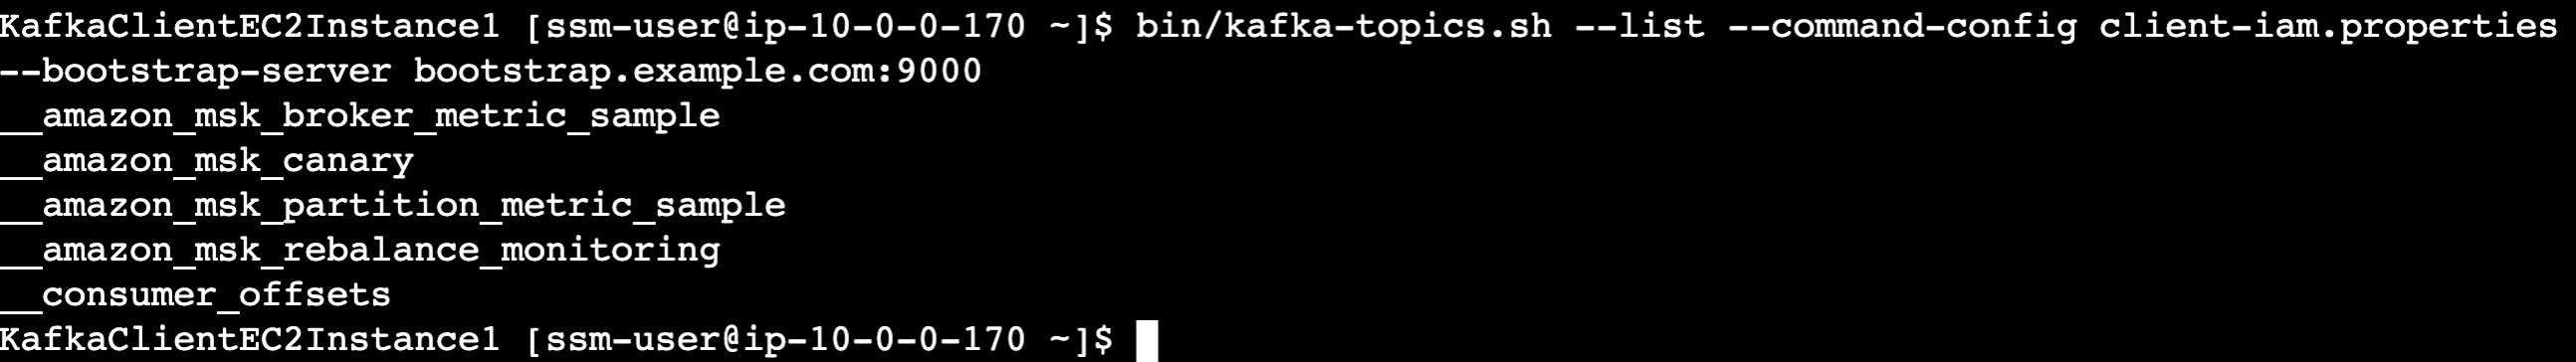
  7. Verify you can connect to the cluster using IAM authentication using our new custom domain name, replacing bootstrap.example.com with your own custom domain name if you used a different one in CloudFormation:
    bin/kafka-topics.sh --list --command-config client-iam.properties --bootstrap-server bootstrap.example.com:9000

Cleanup

To stop incurring costs navigate to CloudFormation and delete the CloudFormation stack to remove all resources provisioned by CloudFormation.

Frequently Asked Question about Custom Domain Name

Customers have asked a few questions about implementing custom domain names with MSK. You can find answers to some of the most popular questions here.

Are there any limitations for this solution on MSK?

The advertised.listeners setting was removed as a dynamic broker in KRaft-based Kafka clusters. Therefore, this solution is only supported in Zookeeper-based MSK clusters. Additionally, this solution is only applicable to SASL/SCRAM and IAM-authentication based MSK clusters.

How the custom domain name solution scales when we add new brokers?

When using the NLB for broker connectivity (option 2 in the configure a custom domain name for your Amazon MSK cluster blog post), you will need to add an additional listener for each additional broker created.

For TLS, if using Subject Alternative Name (SAN) to list individual broker DNS hostnames, you will need to create a new certificate that includes the names of the additional brokers. One option is to create a certificate with SANs for more brokers than needed to allow for growth.If a wildcard certificate is used, you do not need to modify certificates when adding brokers.

What changes are required when we remove brokers?

Amazon MSK supports scale-in by removing brokers from the cluster. Brokers are removed from each availability zones (AZ). So a 6 broker Amazon MSK cluster deployed in 3 AZ can be reduced to 3 broker cluster deployed in 3 AZ. When brokers are removed, you can remove the NLB listeners for the removed broker along with the Route53 DNS endpoints. However, you can also leave them as is, or just remove the target IP from the broker numbers target group. The NLB will mark the targets as unhealthy and stop directing traffic to them. If you ever plan to scale-out the number of brokers, you can re-use the existing NLB listeners and Route 53 DNS entries and would only need to update the target IPs used in the broker numbers target group.

Is there any change in configuration required if there is any broker failure?

No. When a broker fails, Amazon MSK replaces the failed broker with a new broker instance keeping the configuration of the broker exactly the same. So, there would be no change in the advertised listener of the broker. Once the broker is healthy, the broker can accept new connections and read/write traffic.

Can you use Amazon MSK Replicator between MSK clusters in multiple AWS Regions when using the custom domain name solution?

The Amazon MSK Replicator can be used when using the custom domain name solution, either in an active-passive or active-active setup. The same process can be followed to set the custom domain name.

You then follow build multi-Region resilient Apache Kafka applications with identical topic names using Amazon MSK and Amazon MSK Replicator post to configure MSK Replicator.

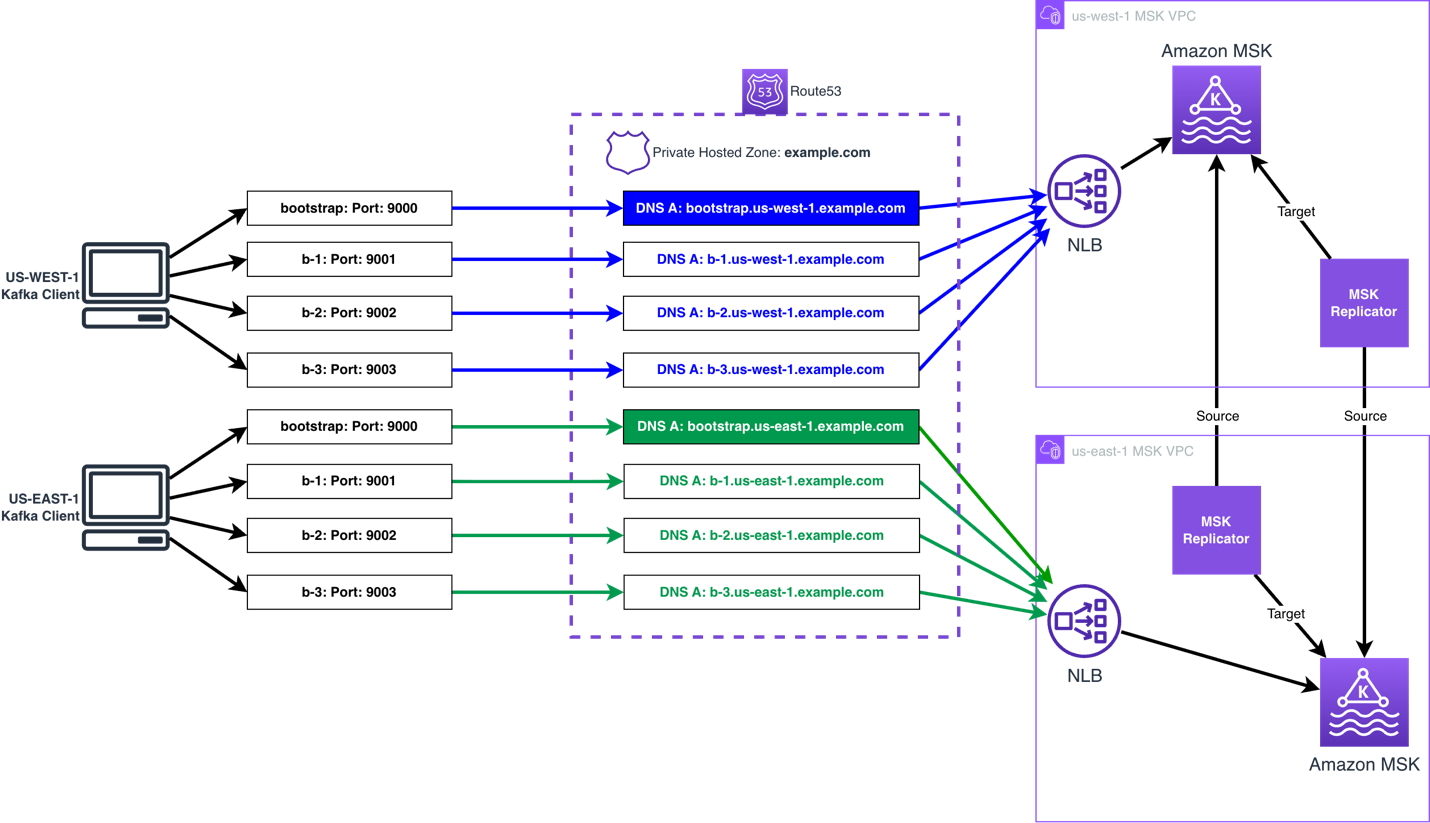
The following diagram shows an active-active AWS multi-Region MSK setup using the custom domain name solution:

Can I use a global bootstrap DNS name to connect to Amazon MSK clusters deployed across multiple AWS regions when IAM authentication is enabled?

No, it is not possible to use a global bootstrap reference to represent MSK clusters deployed in multiple AWS Regions, unless the client is aware of the cluster’s region when connecting. To use IAM authentication, the correct AWS Region must be included in the IAM authentication request for a given cluster. This is because the AWS Region is a part of the Sigv4 authentication protocol used by IAM. This scope prevents the IAM authorization being used to talk to a resource in another AWS Region. You can provide the AWS Region in one of two ways– with region-specific bootstrap URLs or by explicitly configuring the region.

For example, if the bootstrap string is bootstrap.us-east-1.example.com, then msk-iam-auth library will to extract the AWS Region from the broker connection string and use us-east-1 in its IAM requests. If the bootstrap string is simply bootstrap.example.com, then the client must explicitly configure AWS_REGION=us-east-1 to connect to the cluster if it is in us-east-1, or us-west-2 if it is in us-west-2.

Note that this is a limitation for IAM authentication, but not for SASL/SCRAM authentication. With SASL/SCRAM authentication, if the client’s credentials are applied to both clusters the global endpoint can point to either cluster and the client will be able to connect. The AWS Region is not used in SASL/SCRAM authentication, so it does not restrict the authentication scope.

How to allow public access to a private MSK cluster using the custom domain name solution?

To provide public access to a MSK cluster using the custom domain solution, you will need to do the following:

  • Create an Internet-facing NLB, and associate public subnets (subnets that have a route to the Internet Gateway attached to the VPC).
  • Create ingress rules in both the NLB and MSK security groups permitting the required public addresses. Note: the port will be 9098 for the MSK security group, and the ports you are using on the NLB listeners.
  • Provide public DNS resolution for the Kafka clients, by using a Route 53 public zone, or an alternative public DNS resolver.
  • The client needs have IAM credentials, with permission, to talk to the MSK brokers, using an IAM role, IAM access keys, IAM Roles Anywhere, or another mechanism that uses the AWS Security Token Service (AWS STS) to create and provide trusted users with temporary security credentials.

In the first part of the blog, two patterns have been highlighted. How to decide which pattern to use and why?

Option 1: Only bootstrap connection through NLB

If the Kafka clients have direct access to the broker, then you can use custom domain name for the bootstrap connection while the clients can still connect to the MSK Brokers with broker DNS. This is the simplest option, as it does not require custom TLS certificates or TLS listeners.Note that this option is not necessary when using MSK Express brokers, as MSK Express brokers already manages bootstrapping via a broker-agnostic connection string. For MSK Express, this option does not add value other than configuring a custom domain name for appearances / simplicity of client configuration. For MSK Standard brokers, this can improve client connectivity by making connection strings broker agnostic.

Option 2: All connections through NLB

When Kafka clients don’t have direct access to Amazon MSK Brokers, routing all connections through the NLB can be preferred. This can occur when a client is deployed in a different VPC than Amazon MSK VPC or the client is external, and when Amazon MSK Multi VPC Connectivity is not an option. In general, Amazon MSK Multi VPC Connectivity is preferred as this is a simpler pattern for most organizations to manage MSK Connectivity across accounts and VPCs.When Multi VPC Connectivity is not an option, NLB can be used to provide connectivity with Transit Gateway or PrivateLink, and the solution mentioned in the blog should be used.

Here is an example architecture how Kafka client and Amazon MSK cluster deployed in two separate VPCs but connected via AWS Private Link.

Is Amazon Route 53 required to use a custom domain name with Amazon MSK?

You can use an alternative DNS resolver service, and do not require Amazon Route 53 to use a custom domain name with Amazon MSK. The only requirement is that your clients can resolve against your DNS resolver service. The only change required, is to use a CNAME for the DNS records, referencing the NLBs DNS record, in place of the Alias records, as this is record type is only available in Amazon Route 53.

We don’t use Amazon Certificate Manager (ACM), can NLB integrate with other 3rd party certificate managers?

NLB only supports ACM to bind a certificate to a TLS listener. You can import a certificate created using your 3rd party certificate manager into ACM, and do not need to create a certificate using ACM.

Getting connection to node terminated during authentication after setting advertised.listeners , what could be the issue?

As the issue started to occur after changing the advertised.listeners configuration, the issue is unlikely to be related to permissions. The following can cause this issue:

  • The NLB and/or client’s Security Group does not permit access to the listener ports on the NLB from the client.
  • A firewall appliance between the NLB and client does not permit the client to talk to the NLB using the listener ports.
  • The advertised.listeners configuration has an error causing the client to receive invalid details, such as a typo in the name. If this is the case, use a client in the same VPC as the MSK broker that has IAM permissions to talk to the MSK broker, and Security Group rules permitting connectivity, you then use the following command to delete the advertised.listeners configuration.
/home/ec2-user/kafka/bin/kafka-configs.sh --alter \
         --bootstrap-server  \
         --entity-type brokers \
         --entity-name  \
         --command-config ~/kafka/config/client_iam.properties \
         --delete-config advertised.listeners

BROKERS_AMAZON_DNS_NAME such as b-1.clustername.xxxxxx.yy.kafka.region.amazonaws.com:9098.

Getting “unexpected broker id, expected 2 or empty string, but received 1”, what is causing this error?

This error is typically presented when the advertised.listeners configuration for one of the brokers has the port used by another broker set. For example broker 2 has port 9001 set for IAM, but this port is used to connect to broker 1, so broker 1 is responding with an error to say you presented broker id 2, but I am broker 1.

To correct this, you will need to update the broker with the incorrect advertised.listeners configuration to use the correct port. To gain access to the broker to make the change, you will need to use the following command to delete the incorrect configuration:

/home/ec2-user/kafka/bin/kafka-configs.sh --alter \
         --bootstrap-server \
         --entity-type brokers \
         --entity-name  \
         --command-config ~/kafka/config/client_iam.properties \
         --delete-config advertised.listeners

BROKERS_AMAZON_DNS_NAME such as b-2.clustername.xxxxxx.yy.kafka.region.amazonaws.com:9098.

You then need to use the following command to set the advertised.listeners configuration for that broker:

Note: The advertised.listeners configuration in the below assumes only IAM is used for authentication. If you are using additional authentication options, you will need to include them.

MSKDOMAIN=
broker_id=
Domain=

/home/ec2-user/kafka/bin/kafka-configs.sh --alter \
         --bootstrap-server  \
         --entity-type brokers \
         --entity-name "$broker_id" \
         --command-config ~/kafka/config/client_iam.properties \
         --add-config "advertised.listeners=[CLIENT_IAM://b-$broker_id.$Domain:900$broker_id,REPLICATION://b-$broker_id-internal.$MSKDOMAIN:9093,REPLICATION_SECURE://b-$broker_id-internal.$MSKDOMAIN:9095]"

Summary

In this post, we explained how you can use an NLB, Route 53, and the advertised listener configuration option in Amazon MSK to support custom domain names with MSK clusters when using IAM authentication. You can use this solution to keep your existing Kafka bootstrap DNS name and reduce or remove the need to change client applications because of a migration, recovery process, or to use a DNS name in line with your organization’s naming convention (for example, msk.prod.example.com).

Try the solution out for yourself, and leave your questions and feedback in the comments section.


About the authors

Subham Rakshit

Subham Rakshit

Subham is a Senior Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build streaming architectures so they can get value from analyzing their streaming data. His two little daughters keep him occupied most of the time outside work, and he loves solving jigsaw puzzles with them.

Mark Taylor

Mark Taylor

Mark is a Senior Technical Account Manager at AWS, working with enterprise customers to implement best practices, optimize AWS usage, and address business challenges. Mark lives in Folkestone, England, with his wife and two dogs. Outside of work, he enjoys watching and playing football, watching movies, playing board games, and traveling.

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Migrate third-party and self-managed Apache Kafka clusters to Amazon MSK Express brokers with Amazon MSK Replicator

Post Syndicated from Ankita Mishra original https://aws.amazon.com/blogs/big-data/migrate-third-party-and-self-managed-apache-kafka-clusters-to-amazon-msk-express-brokers-with-amazon-msk-replicator/

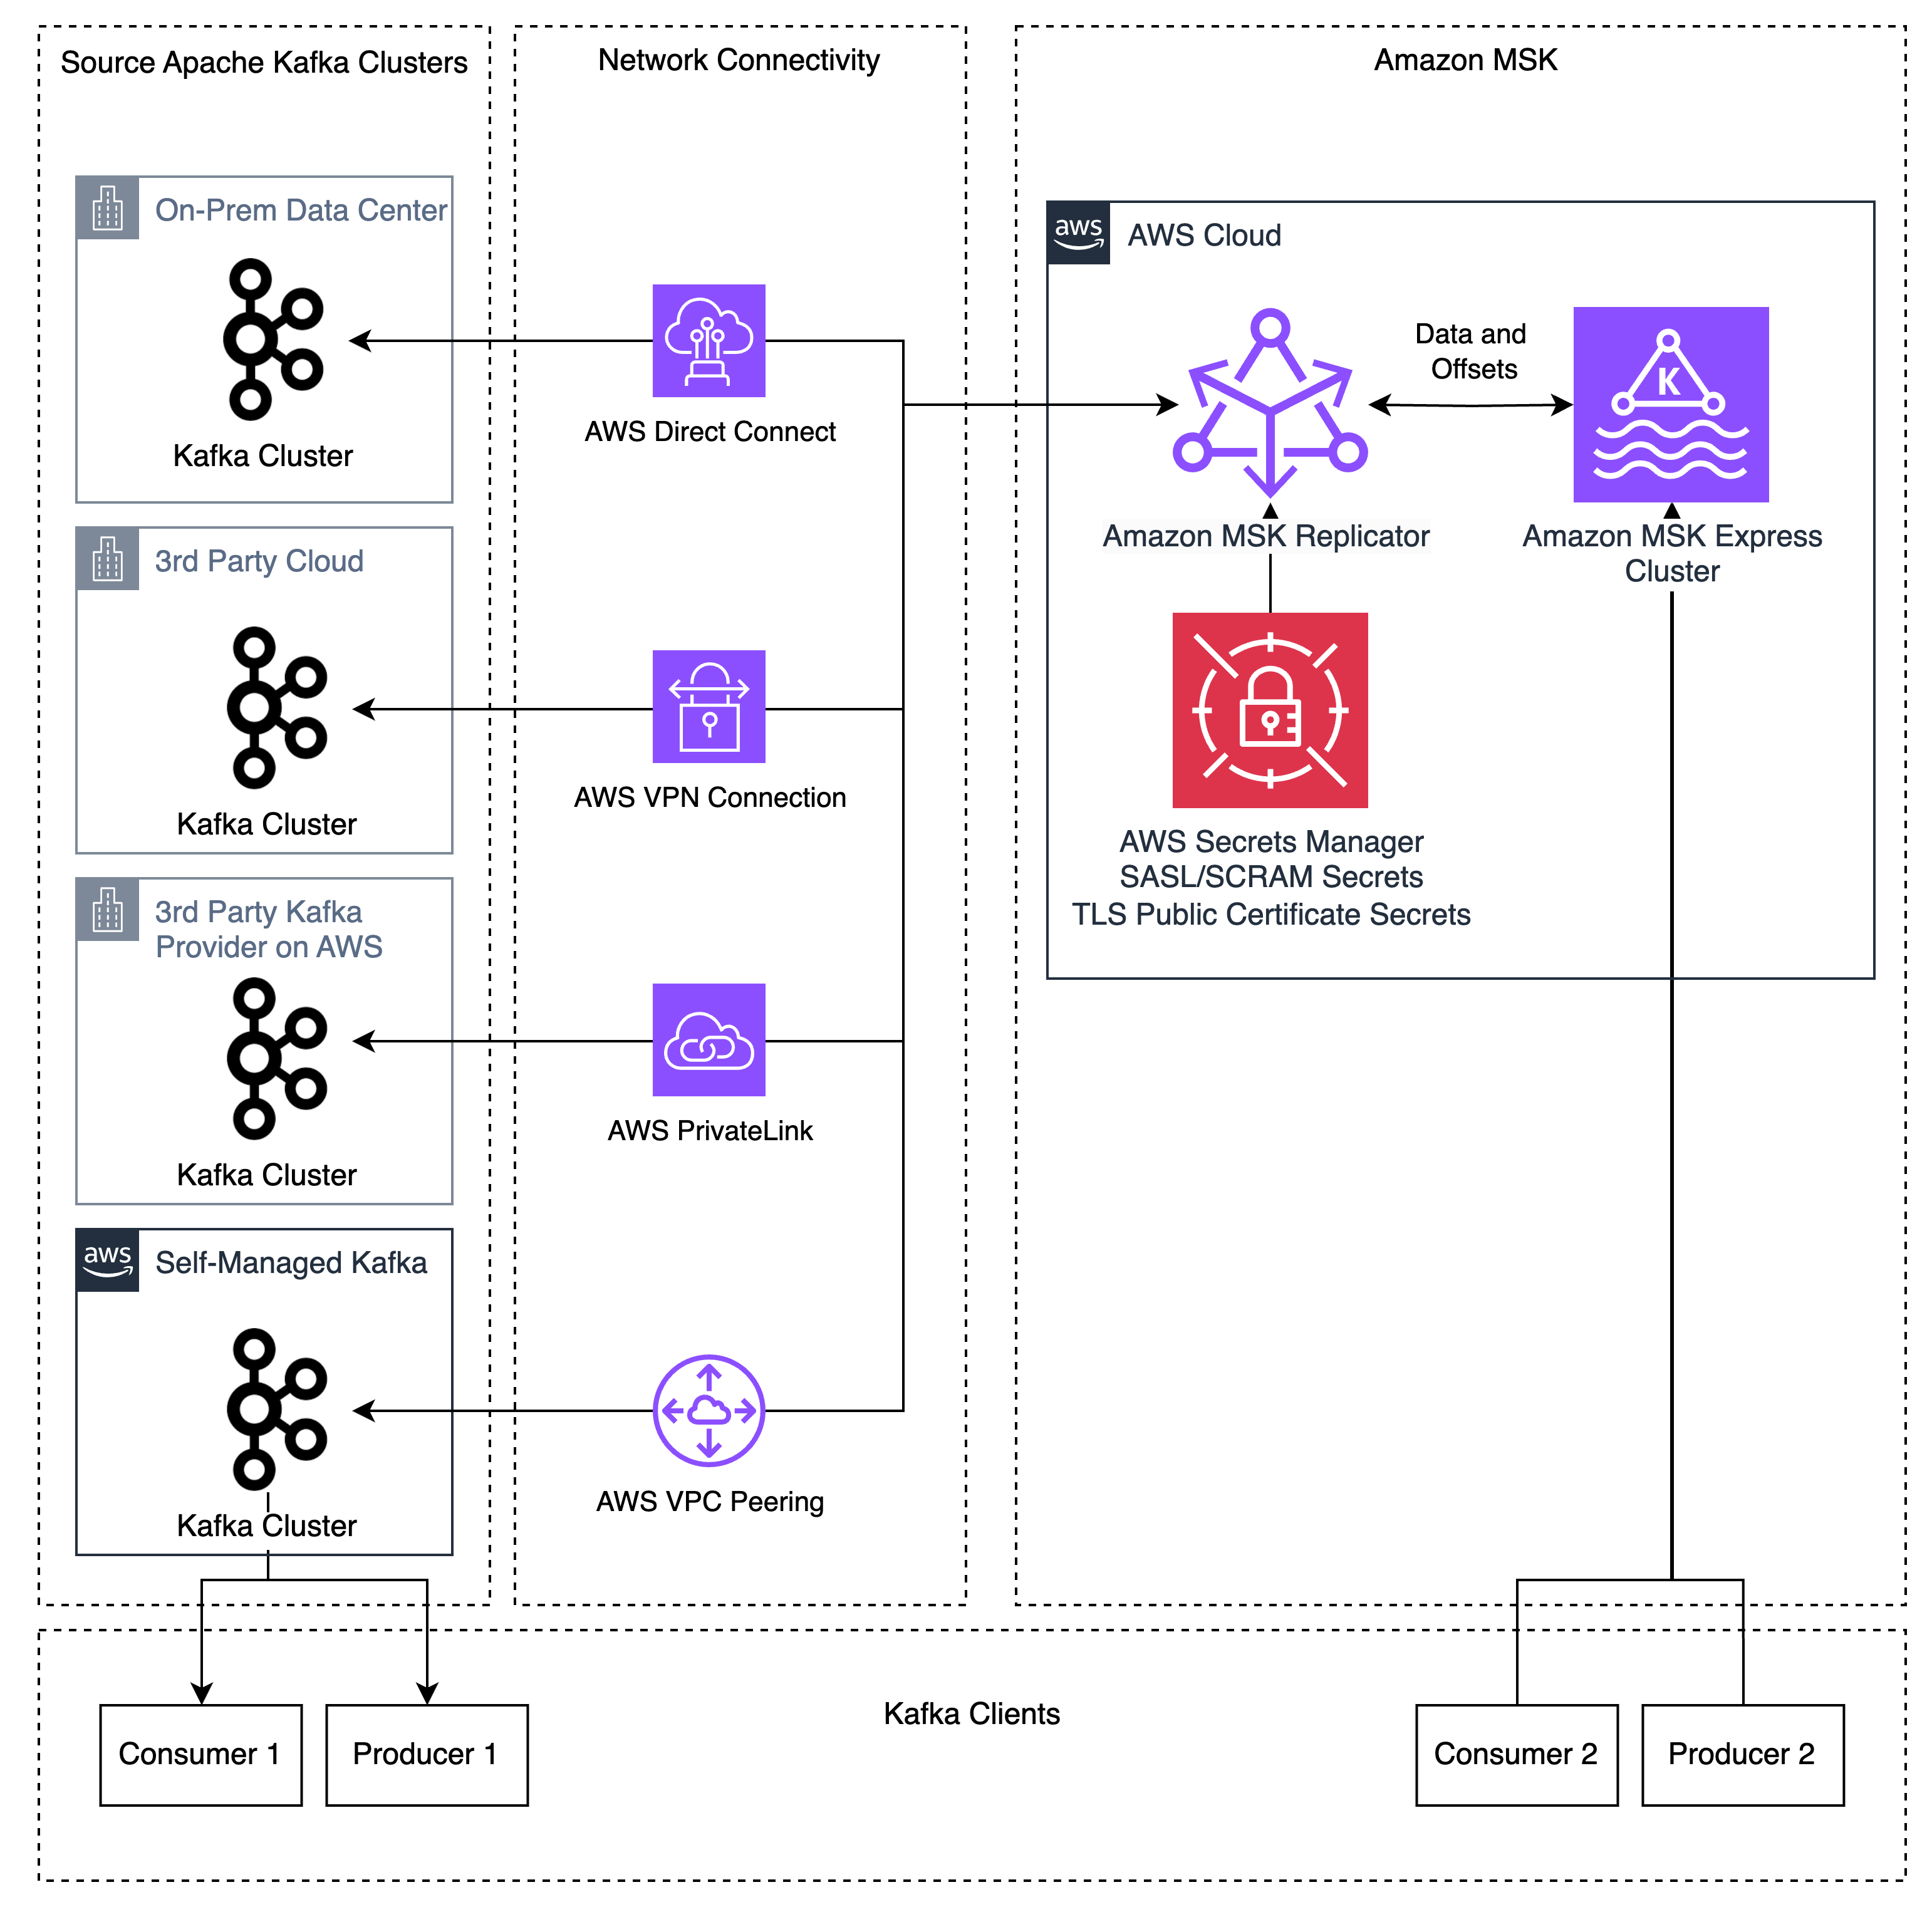
Migrating Apache Kafka workloads to the cloud often involves managing complex replication infrastructure, coordinating application cutovers with extended downtime windows, and maintaining deep expertise in open-source tools like Apache Kafka’s MirrorMaker 2 (MM2). These challenges slow down migrations and increase operational risk. Amazon MSK Replicator addresses these challenges, enabling you to migrate your Kafka deployments (referred to as “external” Kafka clusters) to Amazon MSK Express brokers with minimal operational overhead and reduced downtime. MSK Replicator supports data migration from Kafka deployments (version 2.8.1 or later) that have SASL/SCRAM authentication enabled – including Kafka clusters running on-premises, on AWS, or other cloud providers, as well as Kafka-protocol-compatible services like Confluent Platform, Avien, RedPanda, WarpStream, or AutoMQ when configured with SASL/SCRAM authentication.

In this post, we walk you through how to replicate Apache Kafka data from your external Apache Kafka deployments to Amazon MSK Express brokers using MSK Replicator. You will learn how to configure authentication on your external cluster, establish network connectivity, set up bidirectional replication, and monitor replication health to achieve a low-downtime migration.

How it works

MSK Replicator is a fully managed serverless service that replicates topics, configurations, and offsets from cluster to cluster. It alleviates the need to manage complex infrastructure or configure open-source tools.

Before MSK Replicator, customers used tools like MM2 for migrations. These tools lack bi-directional topic replication when using the same topic names, creating complex application architectures to consume different topics on different clusters. Custom replication policies in MM2 can allow identical topic names, but MM2 still lacks bidirectional offset replication because the MM2 architecture requires producers and consumers to run on the same cluster to replicate offsets. This created complex migrations that required either migrating consumers before producers or big-bang migrations migrating all applications at once. When customers run into issues during the migration, the rollback process is error-prone and introduces large amounts of duplicate message processing due to the lack of consumer group offset synchronization. These approaches create risk and complexity for customers that make migrations difficult to manage.

MSK Replicator addresses these problems by supporting bidirectional replication of data and enhanced consumer group offset synchronization. MSK Replicator copies topics and offsets from an external Kafka cluster to MSK, allowing you to preserve the same topic and consumer group names on both clusters. MSK Replicator also supports creating a second Replicator instance for bidirectional replication of both data and enhanced offset synchronization, allowing producers and consumers to run independently on different Kafka clusters. Data published or consumed on the Amazon MSK cluster will be replicated back to the external cluster by the second Replicator. This feature works when producers and consumers are migrated regardless of order without worrying about dependencies between applications.

Because MSK Replicator provides bidirectional data replication and enhanced consumer group offset synchronization, you can move producers and consumers at your own pace without data loss. This reduces migration complexity, allowing you to migrate applications between your external Kafka cluster and Amazon MSK regardless of order. If you run into problems during the migration, enhanced offset synchronization allows you to roll back changes by moving applications back to the external Kafka cluster, where they restart from the latest checkpoint from the Amazon MSK cluster.

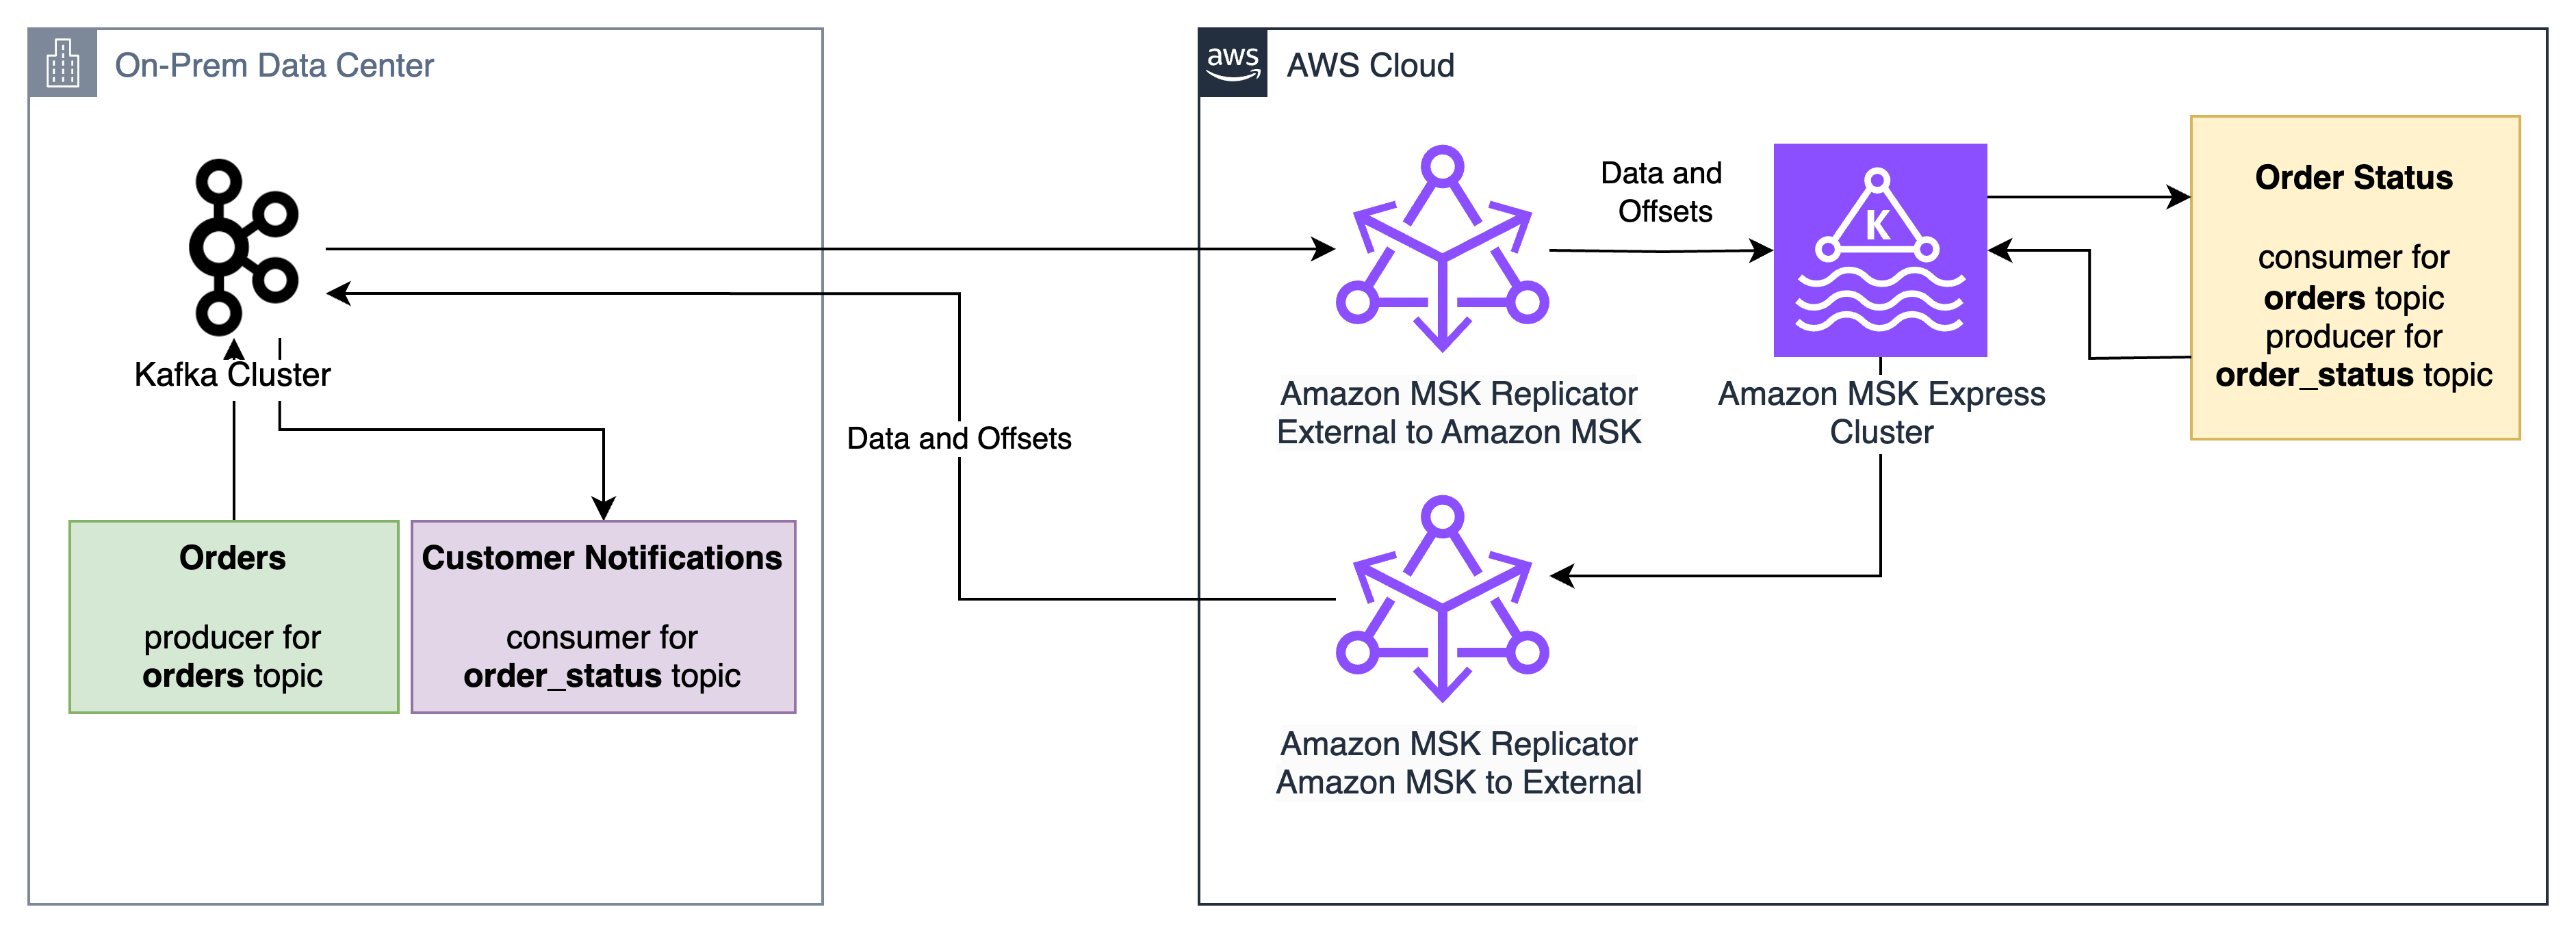
For example, consider three applications:

  1. The “Orders” application, which accepts incoming orders and writes them to the orders Kafka topic
  2. The “Order status” application, which reads from the “orders” Kafka topic and writes status updates to the order_status topic
  3. The “Customer notification” application, which reads from the order_status topic and notifies customers when status changes

MSK Replicator enables these applications to be migrated between an on-premises Apache Kafka cluster and an Amazon MSK Express cluster with low downtime and no data loss, regardless of order. The “Order status” application can migrate first, receive orders from the on-premises “Orders” application, and send status updates to the on-premises “Customer notification” application. If issues arise during the migration, the “Order status” application can roll back to the on-premises cluster and its consumer group offsets for the orders topic will be ready for it to pick up from where it left off on the Amazon MSK cluster.

MSK Replicator supports data distribution across hybrid and multi-cloud environments for analytics, compliance, and business continuity. It is also configured for disaster recovery scenarios where Amazon MSK Express serves as a resilient target for your external Kafka clusters.

If you are currently using MM2 for replication, see Amazon MSK Replicator and MirrorMaker2: Choosing the right replication strategy for Apache Kafka disaster recovery and migrations to understand which solution best fits your use case.

Solution overview

MSK Replicator supports Kafka deployments running version 2.8.1 or later as a source, including 3rd party managed Kafka services, self-managed Kafka, and on-premises or third-party cloud-hosted Kafka. MSK Replicator automatically handles data transfer, uses SASL/SCRAM authentication with SSL encryption, and maintains consumer group positions across both clusters. If you do not use SASL/SCRAM today, this can be configured as a new listener used for MSK Replicator allowing current clients to use their existing authentication mechanisms alongside MSK Replicator.

Prerequisites

To follow along with this walkthrough, you need the following resources in place:

Setting up replication

Step 1: Configure network connectivity

You can set up network connectivity between your external Kafka cluster and your AWS VPC using methods such as AWS Direct Connect for dedicated network connections, AWS Site-to-Site VPN for encrypted connections over the internet, and AWS VPC peering or AWS Transit Gateway for connections between AWS VPCs. Verify that IP routing and DNS resolution are properly configured between your external cluster and AWS.

To verify IP routing and DNS resolution, connect to your external Kafka cluster from inside of your VPC by using the Kafka CLI to list topics on the external cluster. If you can list topics from your VPC using the Kafka CLI, this means DNS resolution and IP routing are working successfully. If it fails, work with your network admins to troubleshoot network connectivity issues.

Step 2: Configure external cluster

In this step, you will set up authentication on your external Kafka cluster and store the credentials in AWS Secrets Manager so that MSK Replicator can connect securely.

Configure authentication

Using the external cluster admin user, configure SASL/SCRAM authentication for MSK Replicator using SHA-256 or 512 on your external Kafka cluster. Create a SASL/SCRAM user for MSK Replicator and give the user the following ACL permissions:

  • Topic operations – Alter, AlterConfigs, Create, Describe, DescribeConfigs, Read, Write
  • Group operations – Read, Describe
  • Cluster operations – Create, ClusterAction, Describe, DescribeConfigs

Configure SecretsManager

AWS Secrets Manager stores your SASL/SCRAM credentials securely so that MSK Replicator can retrieve them at runtime. The secret must use JSON format and have the following keys:

  • username – The SCRAM username that you configured in the authentication step above
  • password – The SCRAM password that you configured in the authentication step above
  • certificate – The public root CA certificate (the top-level certificate authority that issued your cluster’s TLS certificate) and the intermediate CA chain (intermediate certificates between the root and your cluster’s certificate), used for SSL handshakes with the external cluster

Optionally, you may create separate secrets for SCRAM credentials and the SSL certificate. This approach is useful when secrets for SCRAM credentials and certificates are provisioned in different stages, such as in Infrastructure as Code (IaC) pipelines.

Retrieve the cluster ID

As the admin user, use the Kafka CLI tools to retrieve the cluster ID of your external cluster. Run the following command, replacing your-broker-host:9096 with the address of one of your external cluster’s bootstrap servers:

bin/kafka-cluster.sh cluster-id --bootstrap-server your-broker-host:9096 --config admin.properties

The command returns a cluster ID string such as lkc-abc123. Take note of this value because you will need it when creating the replicator in Step 4.

Step 3: Create your MSK Express target cluster

With your external cluster configured, you can now set up the target. Create an Amazon MSK Express cluster with IAM authentication enabled. Make sure that the cluster is in subnets that have access to AWS Secrets Manager endpoints. See Get started using Amazon MSK for more information on creating an MSK cluster.

Step 4: Create the replicator

Now that both clusters are ready, you can connect them by setting up the MSK Replicator with the appropriate IAM role and replication configuration.

Set up an IAM role for MSK Replicator

MSK Replicator needs an IAM role to interact with your MSK Express cluster and retrieve secrets. Set up a service execution IAM role with a trust policy allowing kafka.amazonaws.com and attach the AWSMSKReplicatorExecutionRole permissions policy. Take note of the role ARN for creating the replicator.

Create and attach a policy for accessing your Secrets Manager secrets and reading/writing data in your MSK cluster. See Creating roles and attaching policies (console) for more information on creating IAM roles and policies.

The following is an example policy for reading and writing data to your MSK cluster and reading KMS-encrypted Secrets Manager secrets:

{ 
    "Version": "2012-10-17", 
    "Statement": [ 
        { 
            "Sid": "SecretsManagerAccess", 
            "Effect": "Allow", 
            "Action": [ 
                "secretsmanager:GetSecretValue", 
                "secretsmanager:DescribeSecret" 
            ], 
            "Resource": [ 
                "<SCRAM_SECRET_ARN>", 
                "<CERT_SECRET_ARN>" 
            ] 
        }, 
        { 
            "Sid": "KMSDecrypt", 
            "Effect": "Allow", 
            "Action": "kms:Decrypt", 
            "Resource": "<SECRETSMANAGER_KMS_KEY_ARN>" 
        }, 
        { 
            "Sid": "TargetClusterAccess", 
            "Effect": "Allow", 
            "Action": [ 
                "kafka-cluster:Connect", 
                "kafka-cluster:DescribeCluster", 
                "kafka-cluster:AlterCluster", 
                "kafka-cluster:DescribeClusterDynamicConfiguration", 
                "kafka-cluster:AlterClusterDynamicConfiguration", 
                "kafka-cluster:DescribeTopic", 
                "kafka-cluster:CreateTopic", 
                "kafka-cluster:AlterTopic", 
                "kafka-cluster:DescribeTopicDynamicConfiguration", 
                "kafka-cluster:AlterTopicDynamicConfiguration", 
                "kafka-cluster:WriteData", 
                "kafka-cluster:WriteDataIdempotently", 
                "kafka-cluster:ReadData", 
                "kafka-cluster:DescribeGroup", 
                "kafka-cluster:AlterGroup" 
            ], 
            "Resource": [ 
                "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:cluster/<MSK_CLUSTER_NAME>*/*", 
                "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:topic/<MSK_CLUSTER_NAME>/*", 
                "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:group/<MSK_CLUSTER_NAME>*/*" 
            ] 
        }, 
        { 
            "Sid": "CloudWatchLogsAccess", 
            "Effect": "Allow", 
            "Action": [ 
                "logs:CreateLogStream", 
                "logs:PutLogEvents", 
                "logs:DescribeLogStreams" 
            ], 
            "Resource": "<MSK_REPLICATOR_LOG_GROUP_ARN>" 
        } 
    ] 
}

Create the replicator for external to MSK replication

Use the AWS CLI, API, or Console to create your replicator. Here’s an example using the AWS CLI:

aws kafka create-replicator \
  --replicator-name external-to-msk \
  --service-execution-role-arn "arn:aws:iam::123456789012:role/MSKReplicatorRole" \
  --kafka-clusters file://./kafka-clusters.json \
  --replication-info-list file://./replication-info.json \
  --log-delivery file://./log-delivery.json \
  --region us-east-1

The kafka-clusters.json file defines the source and target Kafka cluster connection information, replication-info.json specifies which topics to replicate and how to handle consumer group offset synchronization, and log-delivery.json specifies the CloudWatch logging configuration. The following tables describe the required parameters:

CLI inputs:

CLI Parameter Description Example
replicator-name The name of the replicator external-to-msk
service-execution-role-arn The ARN for the service execution IAM role you created arn:aws:iam::123456789012:role/MSKReplicatorRole
kafka-clusters The Kafka cluster connection info See below
replication-info-list The replication configuration See below
log-delivery The logging configuration See below

Key kafka-clusters.json inputs:

CLI Parameter Description Example
ApacheKafkaClusterId The cluster ID retrieved in Step 2 lkc-abc123
RootCaCertificate The Secrets Manager ARN containing the public CA certificate and intermediate CA chain arn:aws:secretsmanager:<REGION>:<ACCOUNT_ID>:secret:my-cert
MskClusterArn The ARN for the MSK Express cluster arn:aws:kafka:<REGION>:<ACCOUNT_ID>:cluster/my-cluster/abc-123
SecretArn The Secrets Manager ARN containing the SASL/SCRAM username and password arn:aws:secretsmanager:<REGION>:<ACCOUNT_ID>:secret:my-creds
SecurityGroupIds The security group IDs for MSK Replicator sg-0123456789abcdef0

Key replication-info.json inputs:

CLI Parameter Description Example
TargetCompressionType The compression type to use for replicating data LZ4
TopicsToReplicate The list of topics to replicate (use [“.*”] for all topics) [“my-topic”]
ConsumerGroupsToReplicate The list of consumer groups to replicate [“my-group”]
StartingPosition The point in the Kafka topics to begin replication from (either EARLIEST or LATEST) EARLIEST
ConsumerGroupOffsetSyncMode Whether or not to use enhanced bidirectional consumer group offset synchronization ENHANCED

Note that startingPosition is set to EARLIEST in the configuration below, which means the replicator begins reading from the oldest available offset on each topic. This is the recommended setting for migrations to avoid data loss.

Key log-delivery.json inputs:

CLI Parameter Description Example
Enabled Allows you to enable CloudWatch logging true
LogGroup The CloudWatch logs log group name to log to /msk/replicator/my-replicator

Additional log delivery methods for Amazon S3 and Amazon Data Firehose are supported. In this post, we use CloudWatch logging.

The configs should look like the following for external to MSK replication.

kafka-clusters.json:

[ 
  { 
    "ApacheKafkaCluster": { 
      "ApacheKafkaClusterId": "lkc-abc123", 
      "BootstrapBrokerString": "broker1.example.com:9096" 
    }, 
    "ClientAuthentication": { 
      "SaslScram": { 
        "Mechanism": "SHA512", 
        "SecretArn": "arn:aws:secretsmanager:<REGION>:<ACCOUNT_ID>:secret:my-creds" 
      } 
    }, 
    "EncryptionInTransit": { 
      "EncryptionType": "TLS", 
      "RootCaCertificate": "arn:aws:secretsmanager:<REGION>:<ACCOUNT_ID>:secret:my-cert" 
    } 
  }, 
  { 
    "AmazonMskCluster": { 
      "MskClusterArn": "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:cluster/my-cluster/abc-123" 
    }, 
    "VpcConfig": { 
      "SecurityGroupIds": ["sg-0123456789abcdef0"], 
      "SubnetIds": ["subnet-abc123", "subnet-abc124", "subnet-abc125"] 
    } 
  } 
] 

replication-info.json: 

[ 
  { 
    "SourceKafkaClusterId": "lkc-abc123", 
    "TargetKafkaClusterArn": "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:cluster/my-cluster/abc-123", 
    "TargetCompressionType": "LZ4", 
    "TopicReplication": { 
      "TopicsToReplicate": ["my-topic"], 
      "CopyTopicConfigurations": true, 
      "CopyAccessControlListsForTopics": true, 
      "DetectAndCopyNewTopics": true, 
      "StartingPosition": {"Type": "EARLIEST"}, 
      "TopicNameConfiguration": {"Type": "IDENTICAL"} 
    }, 
    "ConsumerGroupReplication": { 
      "ConsumerGroupsToReplicate": ["my-group"], 
      "SynchroniseConsumerGroupOffsets": true, 
      "DetectAndCopyNewConsumerGroups": true, 
      "ConsumerGroupOffsetSyncMode": "ENHANCED" 
    } 
  } 
] 

log-delivery.json: 

{ 
  "ReplicatorLogDelivery": {
     "CloudWatchLogs": {
       "Enabled": true, 
       "LogGroup": "<LOG_GROUP_NAME>"
     }
  } 
}

Configure bidirectional replication from MSK to the external cluster

To enable bidirectional replication, create a second replicator that replicates in the opposite direction. Use the same IAM role and network configuration from Step 4, but swap the source and target. Replace SourceKafkaClusterId with TargetKafkaClusterId and TargetKafkaClusterArn with SourceKafkaClusterArn in a new msk-to-external-replication-info.json file:

aws kafka create-replicator \
  --replicator-name msk-to-external \
  --service-execution-role-arn "arn:aws:iam::123456789012:role/MSKReplicatorRole" \
  --kafka-clusters file:///./kafka-clusters.json \
  --replication-info-list file:///./msk-to-external-replication-info.json \
  --log-delivery file:///./log-delivery.json \
  --region us-east-1

Monitoring replication health

Monitor your replication using Amazon CloudWatch metrics. Three key metrics to understand are MessageLag, SumOffsetLag, and ReplicationLatency. MessageLag measures how far behind the replicator is from the external cluster in terms of messages not yet replicated, while SumOffsetLag measures how far behind a consumer group is from the latest message in a topic. ReplicationLatency is the amount of latency between the source and target clusters in data replication. When the three reach a sustained low level, your clusters are fully synchronized for both data and consumer group offsets.

To troubleshoot MSK Replicator replication or errors, use the CloudWatch logs to get more details about the health of the replicator. MSK Replicator logs status and troubleshooting information which can be helpful in diagnosing issues like connectivity, authentication, and SSL errors.

Note that the replication is asynchronous, so there will be some lag during replication. The lag will reach zero once a client is shut down during migration to the target cluster. This takes about 30 seconds under normal operations, allowing a low downtime migration without data loss. If your lag is continually increasing or does not reach a sustained low level, this indicates that you have insufficient partitions for high-throughput replication. Refer to Troubleshoot MSK Replicator for more information on troubleshooting replication throughput and lag.

Key metrics include:

  • MessageLag – Monitors the sync between the MSK Replicator and the source cluster. MessageLag indicates the lag between the messages produced to the source cluster and messages consumed by the replicator. It is not the lag between the source and target cluster.
  • ReplicationLatency – Time taken for records to replicate from source to target cluster (ms)
  • ReplicatorThroughput – Average number of bytes replicated per second
  • ReplicatorFailure – Number of failures the replicator is experiencing
  • KafkaClusterPingSuccessCount – Connection health indicator (1 = healthy, 0 = unhealthy)
  • ConsumerGroupCount – Total consumer groups being synchronized
  • ConsumerGroupOffsetSyncFailure – Failures during offset synchronization
  • AuthError – Number of connections with failed authentication per second, by cluster
  • ThrottleTime – Average time in ms a request was throttled by brokers, by cluster
  • SumOffsetLag – Aggregated offset lag across partitions for a consumer group on a topic (MSK cluster-level metric)

For more details on these metrics, see the MSK Replicator metrics documentation.

Your applications are ready to migrate when the following conditions are met. For most workloads, you should expect these metrics to stabilize within a few hours of starting replication. High-throughput clusters may take longer depending on topic volume and partition count.

  • ReplicatorFailure = 0
  • ConsumerGroupOffsetSyncFailure = 0
  • KafkaClusterPingSuccessCount = 1 for both source and target clusters
  • MessageLag < 1,000
    • Your sustained lag may be lower or higher depending on your throughput per partition, message size, and other factors
    • Sustained high message lag usually indicates insufficient partitions for high-throughput replication
  • ReplicationLatency < 90 seconds
    • Your sustained latency may be lower or higher depending on your throughput per partition, message size, and other factors
    • Sustained high latency usually indicates insufficient partitions for high-throughput replication
  • SumOffsetLag is at a sustained low level on both clusters
    • Offset values on the two clusters may not be numerically identical.
    • MSK Replicator translates offsets between clusters so that consumers resume from the correct position, but the raw offset numbers can differ due to how offset translation works. What matters is that SumOffsetLag is at a sustained low level.
  • ConsumerGroupCount (MSK) = Expected count (external cluster)
    • If ConsumerGroupCount is zero or does not match the expected count, then there is an issue in the Replicator configuration or a permissions issue preventing consumer group synchronization

Migrating your applications

With bidirectional consumer offset synchronization, you can migrate your producers and consumers regardless of order. Start by monitoring replication metrics until they reach the target values described in the previous section. Then migrate your applications (producers or consumers) to use the MSK Express cluster endpoints and verify that they are producing and consuming as expected. If you encounter issues, you can roll back by switching applications back to the external cluster. The consumer offset synchronization makes sure that your applications resume from their last committed position regardless of which cluster they connect to.

For a comprehensive, hands-on walkthrough of the end-to-end migration process, explore the MSK Migration Workshop, which provides step-by-step guidance for migrating your Kafka workloads to Amazon MSK.

Security considerations

MSK Replicator uses SASL/SCRAM authentication with SSL encryption for secure data transfer between your external cluster and AWS. The solution supports both publicly trusted certificates and private or self-signed certificates. Credentials are stored securely in AWS Secrets Manager, and the target MSK Express cluster uses IAM authentication for access control.

When configuring security, keep the following in mind:

  • Make sure that the IAM role you create in Step 4 follows the principle of least privileges. Only attach AWSMSKReplicatorExecutionRole and an IAM policy for Secrets Manager with least-privileges access to read secret values and avoid adding broader permissions.
  • Verify that your Secrets Manager secret is encrypted with an AWS KMS key that the MSK Replicator service execution role has permission to decrypt.
  • Confirm that the security groups assigned to MSK Replicator allow outbound traffic to your external cluster’s broker ports (typically 9096 for SASL/SCRAM with TLS) and to the MSK Express cluster.
  • Rotate your SASL/SCRAM credentials periodically and update the corresponding Secrets Manager secret. MSK Replicator picks up the new credentials automatically on the next connection attempt.

Under the AWS shared responsibility model, AWS is responsible for securing the underlying infrastructure that runs MSK Replicator, including the compute, storage, and networking resources. You are responsible for configuring authentication mechanisms (SASL/SCRAM), managing credentials in AWS Secrets Manager, configuring network security (security groups and VPC settings), implementing IAM policies following least privilege, and rotating credentials. For more information, see Security in Amazon MSK in the Amazon MSK Developer Guide.

Cleanup

To avoid ongoing charges, delete the resources you created during this walkthrough. Start by deleting the replicators first, because they depend on the other resources:

aws kafka delete-replicator --replicator-arn <replicator-arn>

After both replicators are deleted, you can remove the following resources if they were created solely for this walkthrough:

  1. The MSK Express cluster (deleting a cluster also removes its stored data, so verify that your applications have fully migrated before proceeding)
  2. The Secrets Manager secrets containing your SASL/SCRAM credentials and certificates
  3. The IAM role and policies created for MSK Replicator

You can verify that a replicator has been fully deleted by running aws kafka list-replicators and confirming it no longer appears in the output.

Conclusion

Amazon MSK Replicator simplifies the process of migrating to Amazon MSK Express brokers and establishes hybrid Kafka architectures. The fully managed service alleviates the operational complexity of managing replication while bidirectional consumer offset synchronization enables flexible, low-risk application migration.

Next Steps

To get started using MSK Replicator to migrate applications to MSK Express brokers, use the MSK Migration Workshop for a hands-on, end-to-end migration walkthrough. The Amazon MSK Replicator documentation includes detailed configuration details to help configure MSK Replicator for your use case. From there, use MSK Replicator to migrate your Apache Kafka workloads to MSK Express broker.

Once your migration is complete, consider exploring multi-region replication patterns for disaster recovery, or integrating your MSK Express cluster with AWS analytics services such as Amazon Data Firehose and Amazon Athena. If you need help planning your migration, reach out to your AWS account team, AWS Support or AWS Professional Services.


About the authors

Ankita Mishra

Ankita is a Product Manager for Amazon Managed Streaming for Apache Kafka. She works closely with AWS customers to understand their needs for real-time analytics and high throughput, low latency streaming workloads. Working backwards from their needs, she helps drive the MSK roadmap and deliver new innovations that help AWS customers focus on building novel streaming applications.

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Building unified data pipelines with Apache Iceberg and Apache Flink

Post Syndicated from Nikhil Jha original https://aws.amazon.com/blogs/big-data/building-unified-data-pipelines-with-apache-iceberg-and-apache-flink/

You can process real-time data from your data lake with Amazon Managed Service for Apache Flink without maintaining two separate pipelines. Yet many teams do exactly that, and the cost adds up fast. In this post, you build a unified pipeline using Apache Iceberg and Amazon Managed Service for Apache Flink that replaces the dual-pipeline approach. This walkthrough is for intermediate AWS users who are comfortable with Amazon Simple Storage Service (Amazon S3) and AWS Glue Data Catalog but new to streaming from Apache Iceberg tables.

The dual-pipeline problem

Traditional dual-pipeline architecture with separate batch and streaming paths, each with its own ingestion, processing, storage, and serving layers, processing the same source data independently.

This dual-pipeline approach creates three problems:

  • Double the infrastructure costs. You run and pay for two separate compute environments, two storage layers, and two sets of monitoring. For example, if you’re spending $10,000/month on separate streaming and batch infrastructure, a meaningful portion of that spend is pure duplication.
  • Data synchronization issues. Your batch and streaming consumers read from different copies of the data, processed at different times. When a transaction shows up in your real-time dashboard but not in your batch report (or vice versa), debugging the inconsistency takes hours.
  • Operational complexity. Two pipelines mean two deployment processes, two failure modes to monitor, and two sets of schema evolution to manage. Your team spends time reconciling systems instead of building features.

Where this pattern fits

Before diving into the implementation, consider whether streaming from your data lake is the right approach for your use case.

Streaming from Apache Iceberg tables works well when you need data available within seconds to minutes and you query recent data frequently, multiple times per hour. Common scenarios include:

  • Operational data stores — Stream customer profile updates to serve downstream applications like recommendation engines. When a customer updates their preferences, those changes reach your operational data store within seconds.
  • Fraud detection — Stream transactions for immediate analysis. Start with a 3-second monitor interval and adjust based on your detection accuracy needs.
  • Live dashboards — Power real-time analytics directly from your lake. This is the strongest starting point if you’re evaluating the approach for the first time, because the feedback loop is immediate and straightforward to validate.
  • Event-driven architectures — Trigger downstream processes based on data changes in your Apache Iceberg tables.

Batch processing remains more cost-effective when you process data once per day or less, or you primarily query historical data. Batch queries on Apache Iceberg tables cost less because they don’t require a continuous Apache Flink runtime.

How Apache Iceberg solves this

Apache Iceberg’s snapshot-based architecture removes the need for a separate streaming pipeline. Think of snapshots like Git commits for your data. Each time you write data to your Iceberg table, Iceberg creates a new snapshot that points to the new data files while preserving references to existing files. Apache Flink reads only the changes between snapshots (the new files that arrived after the last checkpoint), rather than scanning the entire table. Atomicity, Consistency, Isolation, Durability (ACID) transactions prevent your concurrent reads and writes from producing partial or inconsistent results. For example, if your batch extract, transform, and load (ETL) job is writing 10,000 records while your Flink application is reading, ACID transactions mean that your streaming query sees either the complete batch of 10,000 records or none of them, not a partial set that could skew your analytics.

The result is a single pipeline that handles both real-time and batch access from the same data, through the same storage layer, with the same schema.

Solution architecture

Your architecture uses four AWS services and one open source table format working together. The following diagram shows how these components connect, replacing the dual-pipeline pattern shown earlier with a single unified flow.

Unified pipeline architecture with data flowing from Amazon S3 through Apache Iceberg tables, with AWS Glue Data Catalog managing metadata, and Amazon Managed Service for Apache Flink consuming incremental snapshots for near real-time processing.

Your source data lands in Amazon S3 as Apache Iceberg table files. AWS Glue Data Catalog tracks the metadata and schema. When new data arrives, Apache Iceberg creates a new snapshot that your application detects. Your Flink application monitors these snapshots and processes new records incrementally, reading only the files that arrived after the last checkpoint, not the entire table.

You use four main components:

  • Amazon S3 — Foundational storage layer for your data lake
  • Data Catalog — Metadata and schema management for Apache Iceberg tables
  • Apache Iceberg — Table format with snapshot-based streaming capabilities
  • Amazon Managed Service for Apache Flink — Stream processing and incremental consumption

Important notices

Before implementing this solution, evaluate these risks for your environment:

  • Data security: Streaming from data lakes exposes data to additional processing systems. Classify your data before implementation—customer profile updates and transaction data typically contain personally identifiable information (PII) and treat them as confidential. Apply encryption at rest and in transit for confidential data. Key risks include unauthorized data access through misconfigured Amazon S3 bucket policies or overly permissive IAM roles. Mitigations: use the resource-scoped IAM policy and TLS-enforcing bucket policy provided in the Security section.
  • Data integrity: Misconfigured checkpoints or schema changes during streaming can lead to data inconsistency. Mitigations: enable exactly-once processing semantics and test schema evolution in a non-production environment first.
  • Compliance: Verify that real-time data processing meets your regulatory requirements. For workloads subject to HIPAA, confirm that you use HIPAA Eligible Services and have a Business Associate Agreement (BAA) with AWS. For PCI-DSS or GDPR workloads, review the relevant compliance documentation on the AWS Compliance page. Implement data retention policies that comply with your regulatory framework.
  • Cost: Nearly continuous streaming incurs ongoing compute costs. Monitor usage to avoid unexpected charges. Cost estimates in this post are based on pricing as of March 2026 and might change. Verify current pricing on the relevant AWS service pricing pages.
  • Operational: Pipeline failures might impact downstream systems. Implement monitoring and alerting before running in production.

Prerequisites

Before you begin, make sure that you have the following in place. This walkthrough assumes intermediate Python skills (comfortable with functions, error handling, and environment variables), basic Apache Flink concepts (streaming compared to batch processing), and basic AWS Identity and Access Management (AWS IAM) knowledge (creating roles and attaching policies). Plan for approximately 90–120 minutes, including setup, implementation, and testing. First-time setup might take longer as you download dependencies and configure AWS resources. Expected AWS costs: approximately $5–10 if you complete the walkthrough within 2 hours and clean up resources immediately afterward. The primary cost driver is Amazon Managed Service for Apache Flink runtime ($0.11/hour per Kinesis Processing Unit (KPU)). You can minimize costs by stopping your application when not in use.

  • An AWS account with AWS IAM permissions for: s3:GetObject, s3:PutObject, s3:ListBucket on your data bucket; glue:GetDatabase, glue:GetTable for catalog access; and flink:CreateApplication, flink:StartApplication for Amazon Managed Service for Apache Flink
  • An existing Amazon S3 bucket for your data lake
  • An AWS Glue Data Catalog database configured
  • Apache Flink 1.19.1 installed locally
  • Python 3.8 or later
  • Java 11 or a more recent version
  • AWS Command Line Interface (AWS CLI) configured with credentials (aws configure)

Required Java Archive (JAR) dependencies

You need multiple JAR files because your Flink application coordinates between different systems—Amazon S3 for storage, AWS Glue for metadata, Hadoop for file operations, and Apache Iceberg for the table format. Each JAR handles a specific part of this integration. Missing even one causes ClassNotFoundException errors at runtime.

  • iceberg-flink-runtime-1.19-1.6.1.jar — Core Apache Iceberg integration with Apache Flink
  • iceberg-aws-bundle-1.6.1.jar — AWS-specific Apache Iceberg functionality for Amazon S3 and AWS Glue
  • flink-s3-fs-hadoop-1.19.1.jar — Provides Apache Flink read and write access to Amazon S3
  • flink-sql-connector-hive-3.1.3_2.12-1.19.1.jar — Hive metastore connector for catalog compatibility
  • hadoop-common-3.4.0.jar — Core Hadoop libraries required by Apache Iceberg
  • flink-shaded-hadoop-2-uber-2.8.3-10.0.jar — Repackaged Hadoop dependencies that avoid version conflicts with Apache Flink
  • hadoop-hdfs-client-3.4.0.jar — Hadoop Distributed File System (HDFS) client libraries for file system operations
  • flink-json-1.19.1.jar — JSON format support for Apache Flink
  • hadoop-aws-3.4.0.jar — Hadoop integration with AWS services
  • hadoop-client-3.4.0.jar — Hadoop client libraries
  • aws-java-sdk-bundle-1.12.261.jar — AWS SDK for authentication and service access
jars = [
    "flink-s3-fs-hadoop-1.19.1.jar",
    "flink-sql-connector-hive-3.1.3_2.12-1.19.1.jar",
    "hadoop-common-3.4.0.jar",
    "flink-shaded-hadoop-2-uber-2.8.3-10.0.jar",
    "iceberg-flink-runtime-1.19-1.6.1.jar",
    "iceberg-aws-bundle-1.6.1.jar",
    "hadoop-hdfs-client-3.4.0.jar",
    "flink-json-1.19.1.jar",
    "hadoop-aws-3.4.0.jar",
    "hadoop-client-3.4.0.jar",
    "aws-java-sdk-bundle-1.12.261.jar"
]

Technical implementation

The sample code in this post is available under the MIT-0 license.This section walks you through building the streaming pipeline step by step. You create a single Python file, iceberg_streaming.py, with three functions that run in sequence. Your main() function calls them in order: set up the Apache Flink environment, register the Data Catalog, then start the streaming query.

Set up your Apache Flink environment

To prepare your Apache Flink environment:

  1. Download the required JAR files listed in the prerequisites section.
  2. Place the JAR files in a lib directory in your project folder.
  3. Configure your HADOOP_CLASSPATH environment variable to point to the lib directory.
  4. Create your streaming execution environment by adding the following function to iceberg_streaming.py:
def setup_environment():
    """Configure the Flink streaming runtime."""
    try:
        os.environ['HADOOP_CLASSPATH'] = os.path.join(os.getcwd(), 'lib', '*')
        env = StreamExecutionEnvironment.get_execution_environment()
        env.set_parallelism(1)
        settings = EnvironmentSettings.new_instance().in_streaming_mode().build()
        t_env = StreamTableEnvironment.create(env, settings)
        return t_env
    except Exception as e:
        print(f"Failed to initialize Flink environment: {e}")
        raise
  1. Verify your environment by running flink –version. If the command isn’t found, confirm that Apache Flink 1.19.1 is installed and that your PATH includes the Flink bin directory.

Configure AWS Glue Data Catalog

To connect your Flink application to Data Catalog:

  1. Open your iceberg_streaming.py file.
  2. Add the create_iceberg_source() function shown in the following section.
  3. Replace the placeholder values with your actual AWS resources before running. These values are static configuration strings, not user input — do not construct them from external or untrusted sources at runtime.
  4. Save the file.
def create_iceberg_source(t_env):
    """Register the AWS Glue Data Catalog as an Iceberg catalog."""
    try:
        catalog_sql = """
        CREATE CATALOG glue_catalog WITH (
            'type'='iceberg',
            'catalog-impl'='org.apache.iceberg.aws.glue.GlueCatalog',
            'warehouse'='s3://<example-data-lake-bucket>',
            'io-impl'='org.apache.iceberg.aws.s3.S3FileIO',
            'aws.region'='us-east-1',
            'hadoop-conf.fs.s3a.aws.credentials.provider'=
                'com.amazonaws.auth.DefaultAWSCredentialsProviderChain',
            'hadoop-conf.fs.s3a.endpoint'='s3.amazonaws.com',
            'property-version'='1'
        )
        """
        t_env.execute_sql(catalog_sql)
        t_env.use_catalog("glue_catalog")
        t_env.use_database("streaming_db")
    except Exception as e:
        print(f"Failed to configure Iceberg catalog: {e}")
        raise

Set up streaming logic

This function configures Apache Flink to monitor your Apache Iceberg table continuously and process new records as they arrive. Checkpointing runs every 10 seconds to track progress—if the job restarts, it resumes from the last checkpoint rather than reprocessing the entire table.Notice the monitor-interval parameter, it controls how frequently Apache Flink checks for new Apache Iceberg snapshots. A 3-second interval provides near real-time processing but generates approximately 1,200 Amazon S3 LIST API calls per hour (at $0.005 per 1,000 requests, roughly $0.04/month per table based on pricing as of March 2026). For less time-sensitive workloads, increase this to 30s to reduce API costs by 90%.Replace customer_events with the name of your Apache Iceberg table in Data Catalog:

def process_record(row):
    """Validate and process each record from the stream."""
    try:
        if row is None:
            raise ValueError("Received null row")
        required_fields = ["event_type", "timestamp"]
        for field in required_fields:
            if field not in row:
                raise ValueError(f"Missing required field: {field}")
        # Validate field types and content
        if not isinstance(row.get("event_type"), str) or len(row["event_type"]) > 256:
            raise ValueError("event_type must be a string under 256 characters")
        if not isinstance(row.get("timestamp"), (str, int)):
            raise ValueError("timestamp must be a string or integer")
        # Replace with your business logic
        print(f"Processing record: {row}")
    except ValueError as e:
        print(f"Validation error for record {row}: {e}")
    except Exception as e:
        print(f"Error processing record {row}: {e}")
def stream_data(t_env):
    """Start the streaming query and process results."""
    try:
        configuration = t_env.get_config().get_configuration()
        configuration.set_string("table.dynamic-table-options.enabled", "true")
        configuration.set_string("execution.checkpointing.interval", "10000")
        query = """
        SELECT * FROM customer_events /*+ OPTIONS(
            'streaming'='true',
            'monitor-interval'='3s',
            'table.exec.iceberg.cell-based-snapshot'='true'
        ) */
        """
        table_result = t_env.execute_sql(query)
        with table_result.collect() as results:
            for row in results:
                process_record(row)
    except Exception as e:
        print(f"Streaming query failed: {e}")
        raise

Putting it together

Your main() function calls the three steps in order:

def main():
    try:
        t_env = setup_environment()
        create_iceberg_source(t_env)
        stream_data(t_env)
    except Exception as e:
        print(f"Pipeline failed: {e}")
        raise
if __name__ == "__main__":
    main()

Run the pipeline locally:python iceberg_streaming.pyPackage the application and submit it to Amazon Managed Service for Apache Flink using the console or the AWS Command Line Interface (AWS CLI).

Running in production

Moving from a local test to a production deployment requires tuning four areas: performance, monitoring, cost, and security. This section covers the key decisions for each.

Performance tuning

Determine your latency requirements before tuning. For fraud detection, you need subsecond processing. For daily reporting dashboards, you can tolerate minutes of delay.

Partition pruning reduces the amount of data scanned per query. Proper partitioning can significantly reduce query times for time series data partitioned by date. To implement, create your Apache Iceberg table with partition columns (PARTITIONED BY (date_column) in your CREATE TABLE statement), then include partition filters in your WHERE clause: WHERE date_column >= CURRENT_DATE - INTERVAL '7' DAY.

Parallel processing matches your data volume and throughput requirements. For most workloads under 10,000 records per second, a parallelism of 1–4 is sufficient. Scale up incrementally and monitor backpressure metrics (indicators that data arrives faster than your pipeline processes it, causing queuing) to find the right setting.

Checkpoint tuning balances reliability and latency. Consider how much data you can afford to reprocess after a failure. If you process 1,000 records per second with 10-second checkpoints, a failure means reprocessing up to 10,000 records. When that’s acceptable, 10 seconds works well. For faster recovery or higher volumes, reduce to 5 seconds.

Resource allocation — Right-size your Apache Flink cluster to avoid over-provisioning. Monitor CPU and memory utilization during your initial runs and adjust task manager resources accordingly.

Monitoring

Configure your production deployment with the following checkpoint settings. These work well for moderate data volumes (up to 10,000 records per second), providing exactly-once processing semantics. This means that the pipeline processes each record exactly once, even if your application restarts. Adjust the checkpoint interval based on your latency requirements. Add this to your setup_environment() function after creating the table environment.

config_dict = {
    "execution.checkpointing.interval": "30000",
    "execution.checkpointing.mode": "EXACTLY_ONCE",
    "execution.checkpointing.timeout": "600000",
    "state.backend": "filesystem",
    "state.checkpoints.dir": "s3://<example-data-lake-bucket>/checkpoints"
}

Use Amazon CloudWatch to track checkpoint duration, records processed per second, and backpressure metrics. A 10-second checkpoint interval means writing state to Amazon S3 360 times per hour. For a 1 MB state size, that’s approximately 8.6 GB per day in checkpoint storage—at Amazon S3 Standard pricing of $0.023/GB, roughly $0.20/day or $6/month per application based on current pricing. If the checkpoint duration exceeds 50% of your interval, increase the interval or add parallelism.

Cost management

Use Amazon S3 Intelligent-Tiering for your Apache Iceberg data files, which typically have predictable access patterns after initial processing. Configure Apache Iceberg’s table expiration to automatically clean up early snapshots. This can reduce storage costs by an estimated 20–30%, though your results vary depending on write frequency and retention policies.

Right-size your Apache Flink resources based on actual throughput needs. Start with a minimal configuration and scale up based on observed backpressure and checkpoint duration metrics. Use Amazon Elastic Compute Cloud (Amazon EC2) Spot Instances where workload interruptions are acceptable, for example, in development and testing environments.

Set data retention policies on both your Apache Iceberg tables and checkpoint storage to avoid storing data longer than necessary.

Security

Security is a shared responsibility between you and AWS. AWS is responsible for the security of the cloud, including the hardware, software, networking, and facilities that run AWS services. You are responsible for security in the cloud, configuring access controls, encrypting data, and managing your application security. Apply these controls in priority order.

AWS IAM roles — Use AWS IAM roles with least-privilege access, scoped to specific resources. The following example policy restricts permissions to your data lake bucket and AWS Glue catalog:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["s3:GetObject", "s3:PutObject"],
      "Resource": "arn:aws:s3:::<example-data-lake-bucket>/*"
    },
    {
      "Effect": "Allow",
      "Action": "s3:ListBucket",
      "Resource": "arn:aws:s3:::<example-data-lake-bucket>",
      "Condition": {
        "StringEquals": {
          "aws:SourceVpce": "<your-vpc-endpoint-id>"
        }
      }
    },
    {
      "Effect": "Allow",
      "Action": ["glue:GetDatabase", "glue:GetTable"],
      "Resource": [
        "arn:aws:glue:us-east-1:<account-id>:catalog",
        "arn:aws:glue:us-east-1:<account-id>:database/streaming_db",
        "arn:aws:glue:us-east-1:<account-id>:table/streaming_db/*"
      ]
    },
    {
      "Effect": "Allow",
      "Action": ["kms:Decrypt", "kms:GenerateDataKey"],
      "Resource": "arn:aws:kms:us-east-1:<account-id>:key/<your-kms-key-id>"
    }
  ]
}

Scoping permissions to specific Amazon S3 buckets, AWS Glue databases, and AWS Key Management Service (AWS KMS) keys restrict access to only the resources your pipeline requires. Review IAM policies quarterly using the IAM Access Analyzer to identify and remove unused permissions.

Encryption — Configure server-side encryption with AWS Key Management Service (AWS KMS) customer managed keys (SSE-KMS) for your Amazon S3 buckets. Using customer managed keys requires additional review from your security team. Confirm your key management policies, rotation procedures, and access controls before implementation. Enable automatic key rotation annually. For encryption in transit, enforce TLS by adding a bucket policy that denies non-HTTPS access:

{
  "Effect": "Deny",
  "Principal": "*",
  "Action": ["s3:GetObject", "s3:PutObject", "s3:ListBucket"],
  "Resource": [
    "arn:aws:s3:::<example-data-lake-bucket>/*",
    "arn:aws:s3:::<example-data-lake-bucket>"
  ],
  "Condition": {
    "Bool": { "aws:SecureTransport": "false" }
  }
}

Amazon S3 bucket hardening — Enable Block Public Access on your buckets to prevent accidental public exposure:

aws s3api put-public-access-block \
  --bucket <example-data-lake-bucket> \
  --public-access-block-configuration \
  BlockPublicAcls=true,IgnorePublicAcls=true,BlockPublicPolicy=true,RestrictPublicBuckets=true

Enable versioning on buckets that store critical data and checkpoints to protect against accidental deletion. For production environments with sensitive data, consider enabling MFA Delete on versioned buckets. Enable S3 server access logging to track requests for security auditing.

Amazon Virtual Private Cloud (Amazon VPC) –Use Amazon VPC endpoints for private communication between your Apache Flink cluster and AWS services, removing public internet routing by keeping traffic within the AWS network.

Access logging – Enable AWS CloudTrail data events to log Amazon S3 object-level API calls (GetObject, PutObject) and Data Catalog API calls. Store logs in a separate Amazon S3 bucket with restricted access and enable log file integrity validation. Run regular compliance checks using AWS Config.

Operational practices

Set up a continuous integration and continuous deployment (CI/CD) pipeline to automate deployment and testing. Use version control to track schema and code changes. With Apache Iceberg’s schema evolution support, you can add columns without rewriting existing data files. Establish rollback procedures using Apache Iceberg’s snapshot-based architecture, so you can roll back to a previous table state if a bad write corrupts your data.

Troubleshooting

If you run into issues during setup or execution, use the following table to diagnose common errors.

Error Cause Solution
ClassNotFoundException Missing JAR files Check the dependencies in your lib directory and confirm HADOOP_CLASSPATH points to the correct path
Table not found Database name mismatch Check that the database name in t_env.use_database() matches the AWS Glue database where you registered your table
Checkpoint failures Amazon S3 permissions Check that your Amazon S3 bucket policy grants s3:PutObject for the checkpoint location
AWS credential errors Missing AWS IAM configuration Check that the AWS IAM role attached to your Apache Flink application has glue:GetTable, glue:GetDatabase, and s3:GetObject permissions on the relevant resources
Snapshot not found Table modified during query Increase monitor-interval or implement retry logic in your process_record() function
Schema mismatch Table schema changed between snapshots Review Apache Iceberg schema evolution settings and confirm backward compatibility

Clean up

To avoid ongoing charges, delete the resources that you created during this walkthrough.

  1. Stop your Amazon Managed Service for Apache Flink application. Open the Amazon Managed Service for Apache Flink console, choose your application name, choose Stop, and confirm the action. Or use the AWS CLI:

aws kinesisanalyticsv2 stop-application --application-name your-app-name

  1. Delete the Amazon S3 buckets that you created for data storage and checkpoints. For instructions, see Deleting a bucket in the Amazon S3 User Guide.
  2. Remove the Apache Iceberg tables from your Data Catalog.
  3. Delete the AWS IAM roles and policies created specifically for this walkthrough.
  4. If you created an Amazon VPC or Amazon VPC endpoints for testing, delete those resources.

Conclusion

Maintaining separate streaming and batch pipelines doubles your infrastructure costs, creates data synchronization issues, and adds operational complexity that slows your team down. In this post, you replaced that dual-pipeline architecture with a single system built on Apache Iceberg and Amazon Managed Service for Apache Flink. You configured a Flink environment with the required JAR dependencies, connected it to Data Catalog, and implemented streaming queries that read new records incrementally with exactly-once processing semantics. The same data, the same storage layer, the same schema—accessible to both your real-time and batch consumers.

To extend this solution, try these next steps based on your use case:

  • If you’re processing high volumes (>10,000 records/sec): Start with partition pruning. Add PARTITIONED BY (date_column) to your table definition, this typically reduces query times by 60–80%.
  • If you need production monitoring: Implement custom Amazon CloudWatch metrics. Track checkpoint duration, records processed per second, and backpressure to catch issues before they impact your pipeline.
  • If you have variable workloads: Configure auto scaling for your Apache Flink cluster. See the Amazon Managed Service for Apache Flink Developer Guide for detailed guidance.

Share your implementation experience in the comments, your use case, data volumes, latency improvements, and cost reductions help other readers calibrate their expectations. To get started, try the Amazon Managed Service for Apache Flink Developer Guide and the Apache Iceberg documentation on the Apache Iceberg website.


About the authors

Headshot of Nikhil

Nikhil Jha

Nikhil Jha is a Principal Delivery Consultant at AWS Professional Services, helping enterprises navigate complex modernization journeys. He builds data and AI solutions for AWS customers. Outside of work he likes swimming and hiking.

Headshot of Vyas

Vyas Garigipati

Vyas Garigipati is a Delivery Consultant at AWS Professional Services, with experience building scalable, distributed systems. He specializes in designing and building AI-powered, high-availability, multi-region architectures and helps customers deploy resilient, production ready solutions on AWS.

Headshot of Vafa

Vafa Ahmadiyeh

Vafa Ahmadiyeh is a Principal Lead Technologist at AWS, specializing in cloud architecture for the global financial services sector. He partners with major financial institutions to modernize their infrastructure and accelerate their migration to AWS, with a focus on building secure, scalable distributed systems and platforms designed for highly regulated environments.

Headshot of Kaushal

Kaushal (KK) Agrawal

Kaushal (KK) Agrawal is a Principal Technology Delivery Leader for the Digital Native Segment of AWS Professional Services, working with top-tier customers to deliver innovation at the intersection of AI and Cloud.

Securely connecting on-premises data systems to Amazon Redshift with IAM Roles Anywhere

Post Syndicated from Zainab Syeda original https://aws.amazon.com/blogs/big-data/securely-connecting-on-premises-data-systems-to-amazon-redshift-with-iam-roles-anywhere/

Securely connecting on-premises data systems to Amazon Redshift requires removing static credentials while preserving seamless access for your data teams. This solution extends connectivity from your on-premises data centers to Amazon Redshift by using short-lived, auditable credentials. All traffic remains within trusted, private channels.

Developers and data engineers need a process to run ingestion pipelines, Extract, Transform, Load (ETL) jobs, and analytics queries without managing static credentials or complex authentication flows. You can use AWS Identity and Access Management (IAM) Roles Anywhere to obtain temporary security credentials in IAM. This service extends the short-term credential model of AWS beyond the cloud and allows on-premises workloads to authenticate with IAM using X.509 certificates from an existing certificate authority. This approach removes static IAM access keys and applies least-privilege access through IAM policies. Every request is recorded in AWS CloudTrail. Paired with private Domain Name System (DNS) and Amazon Virtual Private Cloud (Amazon VPC) endpoints for Amazon Redshift, it keeps authentication and data flows inside private networks without traversing the public internet.

In this post, you will learn how to use AWS IAM Roles Anywhere with Amazon Redshift for secure, private connections. This removes the need to expose traffic to the public internet or manage long-lived access keys.

The challenge

Organizations connecting on-premises data systems to Amazon Redshift typically choose from several established security patterns, each with tradeoffs in risk, complexity, and operational overhead. Static IAM access keys are straightforward to adopt but require ongoing rotation, secure distribution, and storage across systems. Their long-lived nature increases the impact of accidental exposure in code, configuration files, or logs. Shared database or service credentials can streamline setup but often reduce auditability, weaken least-privilege controls, and create accountability challenges across teams. VPN or private network connections improve network isolation, yet they still require strong application-layer authentication and add infrastructure management burdens. Custom secret-management or credential-brokering solutions can reduce reliance on long-lived credentials, but they introduce additional components that must be built, integrated, and maintained. As organizations scale, these patterns often force tradeoffs between strong security controls and the developer productivity needed to build and operate data pipelines efficiently.

Solution overview

The solution integrates on-premises workloads with Amazon Redshift using IAM Roles Anywhere and the built-in IAM authentication of Amazon Redshift. The core idea is that on-premises workloads use X.509 certificates to obtain short-term IAM credentials, then exchange them for temporary Amazon Redshift database credentials. Both provisioned clusters and serverless workgroups are supported. The architecture consists of these main components:

  • Amazon Redshift Service Endpoint – Handles secure API calls such as GetClusterCredentials, GetCredentials, and GetClusterCredentialsWithIAM. The on-premises workload uses these API endpoints to request temporary database credentials.
  • Amazon Redshift Cluster Endpoint – Provides the connection point for database operations on provisioned Amazon Redshift clusters. After obtaining temporary credentials, applications and tools like JDBC/ODBC drivers or psql connect to the cluster endpoint. They use this connection to execute SQL queries, load data, and perform analytics tasks.
  • Amazon Redshift Serverless Workgroup Endpoint – Serves the same function as the cluster endpoint but for serverless deployments. After temporary credentials are retrieved through the GetCredentials API, applications connect to this endpoint using standard database drivers (JDBC/ODBC) or command line tools like psql to run queries and load data.
  • Certificate authority – For this post, we use AWS Private Certificate Authority (AWS Private CA) as the certificate authority (CA) source. Alternatively, you can integrate with an external CA. For more details, see IAM Roles Anywhere with an external certificate authority.
  • X.509 Certificate – We use a sample private certificate stored in AWS Certificate Manager (ACM) and issued by AWS Private CA.
  • IAM Roles Anywhere – Issues short-term AWS credentials to on-premises processes based on X.509 certificates from an organization’s certificate authority. These temporary credentials allow the workload to assume an IAM role that grants access to Amazon Redshift APIs.

To retrieve temporary credentials using IAM Role Anywhere, we use the credential_process parameter in AWS Command Line Interface (AWS CLI) profile configurations to trigger an external process that generates or retrieves credentials. This post uses X.509 certificates to authenticate and return temporary IAM credentials through IAM Roles Anywhere. The AWS IAM Roles Anywhere Credential Helper is executed to handle the signing process for the CreateSession API, returning credentials in a JSON format that applications and tools can consume.

Amazon Redshift provides several APIs that work together to support temporary, IAM-based authentication for different deployment scenarios. When connecting to a provisioned Amazon Redshift cluster, applications typically use the GetClusterCredentials API, which returns short-term database credentials tied to an IAM role’s permissions. For organizations with fully IAM-managed identities, GetClusterCredentialsWithIAM streamlines this process by automatically mapping the IAM identity to a database user, removing the need to specify usernames manually. In serverless deployments, the GetCredentials API performs the same function, issuing temporary credentials for Amazon Redshift Serverless workgroups based on IAM permissions. Collectively, these APIs keep static credentials from being stored or distributed while offering flexible integration paths for both provisioned and serverless Amazon Redshift architectures.

Flow overview

An on-premises ETL job begins by initiating a request and authenticates with AWS using IAM Roles Anywhere to assume an IAM role securely. After obtaining temporary security credentials, the workload calls the Amazon Redshift service endpoint to execute the GetClusterCredentials API, which returns short-term database credentials. These credentials allow the workload to connect to the Amazon Redshift cluster endpoint through a VPC endpoint. This enables running SQL queries or loading data into the cluster as part of the ETL process.

Prerequisites

You must have the following prerequisites to follow along with this post.

AWS account requirements

  • An AWS account with permissions to deploy AWS CloudFormation templates.
  • Access to AWS CloudShell for exporting a sample private certificate that we create using AWS CloudFormation in a later step.

Remote environment

Network Connectivity requirements

Deploy AWS resources with AWS CloudFormation

  1. Navigate to the AWS CloudFormation console.
  2. Choose Create Stack.
  3. Download the redshift-iamra-template template.
  4. For Specify template, choose Upload a template file and upload redshift-iamra-template.
  5. Choose Next.
  6. Enter a unique name for Stack name. The default value is redshift-test.
  7. Configure the stack parameters. The following table provides default values.
Parameter name Default value Description
VPCCIDR 10.0.0.0/16 CIDR block for the VPC
PrivateSubnet1CIDR 10.0.1.0/24 CIDR block for the first private subnet
PrivateSubnet2CIDR 10.0.2.0/24 CIDR block for the second private subnet
CACommonName redshift-ca.example.com Common Name for the Certificate
CAOrganization Example Corp Organization for the Certificate Authority
CACountry US Country for the Certificate Authority
CAValidityInDays 1826 Validity period in days for the CA Certificate (5 years)
RedshiftClusterIdentifier my-redshift-cluster Identifier for the Amazon Redshift cluster
RedshiftDatabaseName dev Name of the initial database in the Amazon Redshift cluster
RedshiftMasterUsername admin Main username for the Amazon Redshift cluster
RedshiftNodeType ra3.xlplus Node type for the Amazon Redshift cluster
ServerlessNamespace my-serverless-namespace Namespace identifier for Amazon Redshift Serverless
ServerlessWorkgroup my-serverless-workgroup Workgroup identifier for Amazon Redshift Serverless
  1. Select the acknowledgement checkbox and choose Create Stack. Stack deployment takes about 10 minutes to complete.
  1. When stack creation is complete, navigate to the Outputs tab on the AWS CloudFormation console and note down the values for the resources that the stack created.

The following table shows a summarized view of the output values.

Output Description Example value
CertificateAuthorityArn Amazon Resource Name (ARN) of the Private Certificate Authority arn:aws:acm-pca:aa-example-1:111122223333:certificate-authority/a1b2c3d4-5678-90ab-cdef-EXAMPLE22222
ClientCertificateArn ARN of the sample client certificate arn:aws:acm:aa-example-1:111122223333:certificate/a1b2c3d4-5678-90ab-cdef-EXAMPLE11111
ProfileArn ARN of the IAM Roles Anywhere profile arn:aws:rolesanywhere:aa-example-1:111122223333:profile/a1b2c3d4-5678-90ab-cdef-EXAMPLE44444
RedshiftAccessRoleArn ARN of the Amazon Redshift Access role arn:aws:iam::1222345677:role/Redshift-test-RedshiftAccessRole
TrustAnchorArn ARN of the IAM Roles Anywhere profile. You will use this value for configuring credential_process for IAM Roles Anywhere in a later step. arn:aws:rolesanywhere:aa-example-1:111122223333:trust-anchor/a1b2c3d4-5678-90ab-cdef-EXAMPLE33333
RedshiftClusterEndpoint Private endpoint of the Amazon Redshift Cluster my-redshift-cluster-123456789012.aa-example-1.redshift.amazonaws.com
RedshiftClusterPort Port of the Amazon Redshift Cluster 5439
ServerlessWorkgroupEndpoint Private endpoint of Amazon Redshift Serverless Workgroup my-serverless-workgroup-123456789012.aa-example-1.redshift.serverless.amazonaws.com

Export a sample private certificate using CloudShell

To export a sample private certificate using CloudShell, complete the following steps.

  1. Open CloudShell. For more details, see Navigating the AWS CloudShell interface.
  2. Export the certificate ARN from the CloudFormation outputs. If you changed the stack name in the previous step, use that value for <stack-name>. Otherwise, use the default value redshift-public-iam-roles-anywhere.
export CERT_ARN=$(aws cloudformation describe-stacks \
    --stack-name <stack-name> \
    --query 'Stacks[0].Outputs[?OutputKey==`ClientCertificateArn`].OutputValue' \
    --output text)
  1. Extract the certificate and private key files:
# Generate and save the passphrase
export PASSPHRASE=$(openssl rand -base64 32)
# Export certificate using environment variables
aws acm export-certificate \
    --certificate-arn $CERT_ARN \
    --passphrase $(echo -n "$PASSPHRASE" | base64) \
    > cert_export.json
# Extract components to separate files
jq -r '.Certificate' cert_export.json > certificate.pem
jq -r '.PrivateKey' cert_export.json > encrypted_private_key.pem
# Decrypt the private key
openssl rsa -in encrypted_private_key.pem -out private_key.pem -passin pass:"$PASSPHRASE"
# Clear environment variables
unset PASSPHRASE CERT_ARN
  1. Download the extracted certificate and private key files from CloudShell:
/home/cloudshell-user/certificate.pem
/home/cloudshell-user/private_key.pem
  1. Secure the private key on your local workstation.

After downloading the files, restrict file permissions to prevent unauthorized access:

chmod 400 private_key.pem chmod 400 certificate.pem

For production workloads, consider storing private keys in your operating system’s keychain (macOS Keychain, Windows Certificate Store), a hardware security module (HSM), or a secrets management tool rather than as files on disk.

Configure an AWS CLI profile

These are the steps to configure an AWS CLI profile on your system:

  1. Store the downloaded certificate and private key to your environment. For an automated approach to generate and rotate certificates, see Set up AWS Private Certificate Authority to issue certificates for use with IAM Roles Anywhere.
  2. Create a new profile named onprem-redshift. This invokes the credential process. Replace the placeholders with your specific values. Find the values for trusted-anchor-arn, profile-arn, and role-arn in your CloudFormation stack outputs.
aws configure set profile.onprem-redshift.credential_process "</path/to/aws_signing_helper> credential-process \
      --certificate </path/to/certificate.pem> \
      --private-key </path/to/private_key.pem> \
      --trust-anchor-arn <trusted-anchor-arn> \
      --profile-arn <profile-arn> \
      --role-arn < role-arn>"
  1. Verify your configuration. Open the ~/.aws/config file and confirm that it contains a profile.
[profile onprem-redshift]
credential_process = </path/to/aws_signing_helper> credential-process       
--certificate </path/to/certificate.pem>       
--private-key </path/to/private_key.pem>       
--trust-anchor-arn <trusted-anchor-arn>       
--profile-arn <profile-arn>       
--role-arn <role-arn>

Test the solution

Follow these steps to validate your setup for provisioned clusters to confirm end-to-end connectivity:

  1. Verify network connectivity

Before testing authentication, confirm that your on-premises environment can reach the Amazon Redshift cluster endpoint:

telnet my-redshift-cluster.abc123.us-east-1.redshift.amazonaws.com 5439

If the connection succeeds, you should see a response indicating the port is open. If it fails, verify your VPN/Direct Connect configuration and security group rules.

  1. Create database user

If you haven’t already created a user, connect to your Amazon Redshift as the main user and create a dedicated user for testing:

CREATE USER analytics_user PASSWORD '[PASSWORD]';

  1. Retrieve Amazon Redshift database credentials

With the configuration in place, request temporary database credentials from Amazon Redshift:

aws redshift get-cluster-credentials \
  --db-user analytics_user \
  --cluster-identifier my-redshift-cluster \
  --region us-east-1 \
  --profile onprem-redshift

This call returns a short-lived username and password that’s valid for connecting to the cluster. By default, the temporary credentials expire in 900 seconds. You can optionally specify a duration between 900–3600 seconds (15–60 minutes).
  1. Connect using JDBC/ODBC or psql

Use the issued credentials in your connection string. For JDBC:

jdbc:redshift://my-redshift-cluster.abc123.redshift.amazonaws.com:5439/dev?ssl=true&UID=analytics_user&PWD=<temporary_password>

For psql:

PGPASSWORD=<temporary_password> psql \
  -h my-redshift-cluster.abc123.redshift.amazonaws.com \
  -p 5439 \
  -U analytics_user \
  -d dev \
  --set=sslmode=verify-full

Validate and monitor

  • Test authentication flows end-to-end using your ETL jobs.
  • Review AWS CloudTrail logs to validate. It records role assumptions and Amazon Redshift API calls.
  • Monitor session expiration to help workloads handle credential refresh seamlessly.

Testing end-to-end connectivity for Amazon Redshift Serverless

The testing process for Amazon Redshift Serverless follows a similar pattern to provisioned clusters, with minor differences in the API calls and connection parameters. These steps validate connectivity to your serverless workgroup.

  1. Verify network connectivity

telnet my-serverless-workgroup.abc123.us-east-1.redshift.amazonaws.com 5439

  1. Retrieve Amazon Redshift Serverless database credentials
aws redshift-serverless get-credentials \
  --workgroup-name my-serverless-workgroup \
  --db-name dev \
  --region us-east-1 \
  --profile onprem-redshift
  1. Connect using JDBC/ODBC or psql
PGPASSWORD="<password_from_get_credentials>" psql \
  -h my-serverless-workgroup.abc12.us-east-1.redshift-serverless.amazonaws.com \
  -p 5439 \
  -U "IAMR:Redshift-IAMRA-RedshiftAccessRole" \
  -d dev \
  --set=sslmode=verify-full

Clean up

To avoid future charges, remove the deployed resources:

  1. Delete the CloudFormation stack.
  2. Remove the generated files from CloudShell:

rm cert_export.json encrypted_private_key.pem certificate.pem private_key.pem

Conclusion

In this post, we showed how to implement IAM Roles Anywhere with Amazon Redshift so that enterprises can securely connect on-premises data systems to their cloud data warehouse without relying on static credentials or public internet access. This architecture provides short-lived, auditable credentials, integrates with existing certificate authorities, and helps ensure authentication and data flows remain private and trusted.

With this approach, data engineers and developers can run ingestion pipelines, ETL jobs, and analytics queries, while security teams maintain full control through IAM governance and CloudTrail auditing. You can remove manual credential rotation tasks, allow your data engineers to connect to Amazon Redshift without managing static keys, and achieve complete audit trails through CloudTrail integration for your hybrid analytics environments.

To get started, deploy the solution using the CloudFormation template and follow the steps in this post. To learn more about the services used, see the following resources:


About the authors

Kanwar Bajwa is a Principal Enterprise Account Engineer at AWS who works with customers to optimize their use of AWS services and achieve their business objectives.

Xiaoxue Xu is a Solutions Architect for AWS based in Toronto. She primarily works with Financial Services customers to help secure their workload and design scalable solutions on the AWS Cloud.

Zainab Syeda is a Technical Account Manager at Amazon Web Services in Toronto. She works with customers in the Financial Services segment, helping them leverage cloud-native solutions at scale.

Getting started with Apache Iceberg write support in Amazon Redshift – Part 2

Post Syndicated from Sanket Hase original https://aws.amazon.com/blogs/big-data/getting-started-with-apache-iceberg-write-support-in-amazon-redshift-part-2/

In Getting started with Apache Iceberg write support in Amazon Redshift – part 1, you learned how to create Apache Iceberg tables and write data directly from Amazon Redshift to your data lake. You set up external schemas, created tables in both Amazon Simple Storage Service (Amazon S3) and S3 Tables, and performed INSERT operations while maintaining ACID (Atomicity, Consistency, Isolation, Durability) compliance.

Amazon Redshift now supports DELETE, UPDATE, and MERGE operations for Apache Iceberg tables stored in Amazon S3 and Amazon S3 table buckets. With these operations, you can modify data at the row level, implement upsert patterns, and manage the data lifecycle while maintaining transactional consistency using familiar SQL syntax. You can run complex transformations in Amazon Redshift and write results to Apache Iceberg tables that other analytics engines like Amazon EMR or Amazon Athena can immediately query.

In this post, you work with customer and orders datasets that were created and used in the previously mentioned post to demonstrate these capabilities in a data synchronization scenario.

Solution overview

This solution demonstrates DELETE, UPDATE, and MERGE operations for Apache Iceberg tables in Amazon Redshift using a common data synchronization pattern: maintaining customer records and orders data across staging and production tables. The workflow includes three key operations:

  • DELETE – Remove customer records based on opt-out requests
  • UPDATE – Modify existing customer information
  • MERGE – Synchronize order data between staging and production tables using upsert patterns
Figure : solution overview

Figure 1: solution overview

The solution uses a staging table (orders_stg) stored in an S3 table bucket for incoming data and reference tables (customer_opt_out) in Amazon Redshift for managing data lifecycle operations. With this architecture, you can process changes efficiently while maintaining ACID compliance across both storage types.

Prerequisites

For this walkthrough, you should have completed the setup steps from Getting started with Apache Iceberg write support in Amazon Redshift – part 1, including:

  • Create an Amazon Redshift data warehouse (provisioned or Serverless)
  • Set up the required IAM role (RedshifticebergRole) with appropriate permissions
  • Create an Amazon S3 bucket and S3 Table bucket
  • Configure AWS Glue Data Catalog database and setting up access
  • Set up AWS Lake Formation permissions
  • Create the customer Apache Iceberg table in Amazon S3 standard buckets with sample customer data
  • Create the orders Apache Iceberg table in Amazon S3 Table buckets with sample order data
  • Amazon Redshift data warehouse on p200 version or higher

Data preparation

In this section, you set up the sample data needed to demonstrate MERGE, UPDATE, and DELETE operations. To prepare your data, complete the following steps:

  1. Log in to Amazon Redshift using Query Editor V2 with the Federated user option.
  2. Create the orders_stg and customer_opt_out tables with sample data:
CREATE TABLE "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders_stg
(
customer_id BIGINT,
order_id BIGINT,
Total_order_amt DECIMAL(10,2),
Total_order_tax_amt REAL,
tax_pct DOUBLE PRECISION,
order_date DATE,
order_created_at_tz TIMESTAMPTZ,
is_active_ind BOOLEAN
)
USING ICEBERG;
INSERT INTO "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders_stg
(order_date, order_id, customer_id, total_order_amt, total_order_tax_amt, tax_pct, order_created_at_tz, is_active_ind)
VALUES
('2024-11-11', 1016, 10, 167.45, 13.40, 0.08, '2024-11-11 06:55:00-06:00', true),
('2024-11-12', 1017, 15, 34.99, 2.80, 0.08, '2024-11-12 23:30:30-06:00', true),
('2024-11-09', 1014, 9, 500.60, 56.80, 0.09, '2024-11-09 16:20:55-06:00', true),
('2024-11-10', 1015, 5, 329.85, 33.51, 0.08, '2024-11-10 11:45:30-06:00', true);
select * from "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders_stg;
Figure 2: orders_stg result set

Figure 2: orders_stg result set

CREATE TABLE dev.public.customer_opt_out
(
customer_id bigint,
customer_name varchar,
opt_out_ind char(1),
cust_rec_upd_ind char(1)
);
INSERT INTO dev.public.customer_opt_out VALUES
(9, 'Customer9 Martinez', 'Y', 'N'),
(12, 'Customer12 Thomas', 'Y', 'N'),
(13, 'Customer13 Albon', 'N', 'Y'),
(14, 'Customer14 Oscar', 'N', 'Y');
select * from dev.public.customer_opt_out;
Figure 3: customer_opt_out result set

Figure 3: customer_opt_out result set

You can now use the orders_stg and customer_opt_out tables to demonstrate data manipulation operations on the orders and customer tables created in the prerequisite section.

MERGE

MERGE conditionally inserts, updates, or deletes rows in a target table based on the results of a join with a source table. You can use MERGE to synchronize two tables by inserting, updating, or deleting rows in one table based on differences found in the other table.

To perform a MERGE operation:

  1. Verify that the current data in the orders table for order IDs 1014, 1015, 1016, and 1017.You loaded this sample data in Part 1:
select * from "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders
where order_id in (1014,1015,1016,1017);
Figure 4: orders data for existing orders for orders in orders_stg

Figure 4: orders data for existing orders for orders in orders_stg

The orders table contains existing rows for order IDs 1014 and 1015.

  1. Run the following MERGE operation using order_id as the key column to match rows between the orders and orders_stg tables:
MERGE INTO "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders
USING "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orders_stg
ON orders.order_id = orders_stg.order_id
WHEN MATCHED THEN UPDATE 
SET
customer_id         = orders_stg.customer_id,
total_order_amt     = orders_stg.total_order_amt,
total_order_tax_amt = orders_stg.total_order_tax_amt,
tax_pct             = orders_stg.tax_pct,
order_date          = orders_stg.order_date,
order_created_at_tz = orders_stg.order_created_at_tz,
is_active_ind       = orders_stg.is_active_ind
WHEN NOT MATCHED THEN INSERT
VALUES 
(orders_stg.customer_id,orders_stg.order_id,orders_stg.total_order_amt,orders_stg.total_order_tax_amt,orders_stg.tax_pct,orders_stg.order_date,orders_stg.order_created_at_tz,orders_stg.is_active_ind);

The operation updates existing rows (1014 and 1015) and inserts new rows for order IDs that don’t exist in the orders table (1016 and 1017).

  1. Verify the updated data in the orders table:
select * from "iceberg-write-blog@s3tablescatalog".iceberg_write_namespace.orderswhere order_id in (1014,1015,1016,1017);
Figure 5: merged data on orders from orders_stg

Figure 5: merged data on orders from orders_stg

The MERGE operation performs the following changes:

  • Updates existing rows – Order IDs 1014 and 1015 have updated total_order_amt and total_order_tax_amt values from the orders_stg table
  • Inserts new rows – Order IDs 1016 and 1017 are inserted because they don’t exist in the orders table

This demonstrates the upsert pattern, where MERGE conditionally updates or inserts rows based on the matching key column.

UPDATE

UPDATE modifies existing rows in a table based on specified conditions or values from another table.

Update the customer Apache Iceberg table using data from the customer_opt_out Amazon Redshift native table. The UPDATE operation uses the cust_rec_upd_ind column as a filter, updating only rows where the value is ‘Y’.

To perform an UPDATE operation:

  1. Verify the current customer_name values for customer IDs 13 and 14 in customer_opt_out and customer (loaded this sample data in Part 1) tables:
select * from dev.public.customer_opt_out
where cust_rec_upd_ind = 'Y';
Figure 6: verify existing customer data for customers from customer_opt_out

Figure 6: verify existing customer data for customers from customer_opt_out

select customer_id,customer_name from dev.demo_iceberg.customer
where customer_id in(13,14);
Figure 7: verify existing customer name for customers from customer_opt_out

Figure 7: verify existing customer name for customers from customer_opt_out

  1. Run the following UPDATE operation to modify customer names based on the cust_rec_upd_ind from customer_opt_out:
UPDATE dev.demo_iceberg.customerSET customer_name = customer_opt_out.customer_name
FROM dev.public.customer_opt_out
WHERE customer_opt_out.cust_rec_upd_ind = 'Y'and customer.customer_id = customer_opt_out.customer_id;
  1. Verify the changes for customer IDs 13 and 14:
select customer_id,customer_name from dev.demo_iceberg.customer where customer_id in(13,14) order by 1;
Figure 8: updated customer names in customer table

Figure 8: updated customer names in customer table

The UPDATE operation modifies the customer_name values based on the join condition with the customer_opt_out table. Customer IDs 13 and 14 now have updated names (Customer13 Albon and Customer14 Oscar).

DELETE

DELETE removes rows from a table based on specified conditions. Without a WHERE clause, DELETE removes all the rows from table.

Delete rows from the customer Apache Iceberg table using data from the customer_opt_out Amazon Redshift native table. The DELETE operation uses the opt_out_ind column as a filter, removing only rows where the value is ‘Y’.

To perform a DELETE operation:

  1. Verify the opt-out indicator data in the customer_opt_out table:
select * from dev.public.customer_opt_out
where opt_out_ind = 'Y';
Figure 9: verify customer records for opt out

Figure 9: verify customer records for opt out

  1. Verify the current customer data for customer IDs 9 and 12:
select * from dev.demo_iceberg.customerwhere customer_id in(9,12);
Figure 0: verify existing customers data in customer table for opt out

Figure 10: verify existing customers data in customer table for opt out

  1. Review the query execution plan:
EXPLAINDELETE FROM demo_iceberg.customerUSING public.customer_opt_out
WHERE customer.customer_id = customer_opt_out.customer_id
AND customer_opt_out.opt_out_ind = 'Y';
Figure 1: query plan for the DELETE queryThe execution plan shows Amazon S3 scans for Apache Iceberg format tables, indicating that Amazon Redshift removes rows directly from the Amazon S3 bucket.

Figure 11: query plan for the DELETE query. The execution plan shows Amazon S3 scans for Apache Iceberg format tables, indicating that Amazon Redshift removes rows directly from the Amazon S3 bucket.

  1. Run the following DELETE operation:
DELETE FROM demo_iceberg.customer
USING public.customer_opt_out
WHERE customer.customer_id = customer_opt_out.customer_id
AND customer_opt_out.opt_out_ind = 'Y';
  1. Verify that the rows were removed:
select * from dev.demo_iceberg.customer where customer_id in(9,12);
Figure 2: result set from customer table for opt out customer after delete

Figure 12: result set from customer table for opt out customer after delete

The query returns no rows, confirming that customer IDs 9 and 12 were successfully deleted from the customer table.

Best practices

After performing multiple UPDATE or DELETE operations, consider running table maintenance to optimize read performance:

  • For AWS Glue tables – Use AWS Glue table optimizers. For more information, see Table optimizers in the AWS Glue Developer Guide.
  • For S3 Tables – Use S3 Tables maintenance operations. For more information, see S3 Tables maintenance in the Amazon S3 User Guide.

Table maintenance merges and compacts deletion files generated by Merge-on-Read operations, improving query performance for subsequent reads.

Conclusion

You can use Amazon Redshift support for DELETE, UPDATE, and MERGE operations on Apache Iceberg tables to build data architectures that combine warehouse performance with data lake scalability. You can modify data at the row level while maintaining ACID compliance, giving you the same flexibility with Apache Iceberg tables as you have with native Amazon Redshift tables.

Get started:


About the authors

Sanket Hase

Sanket Hase

Sanket is an Engineering Manager with the Amazon Redshift team, leading query execution teams in the areas of data lake analytics, hardware-software co-design, and vectorized query execution.

Raghu Kuppala

Raghu Kuppala

Raghu is an Analytics Specialist Solutions Architect experienced working in the databases, data warehousing, and analytics space. Outside of work, he enjoys trying different cuisines and spending time with his family and friends.

Ritesh Sinha

Ritesh is an Analytics Specialist Solutions Architect based out of San Francisco. He has helped customers build scalable data warehousing and big data solutions for over 16 years. He loves to design and build efficient end-to-end solutions on AWS. In his spare time, he loves reading, walking, and doing yoga.

Sundeep Kumar

Sundeep Kumar

Sundeep is a Sr. Specialist Solutions Architect at Amazon Web Services (AWS), helping customers build data lake and analytics platforms and solutions. When not building and designing data lakes, Sundeep enjoys listening to music and playing guitar.

Upgrade business messaging with RCS on AWS

Post Syndicated from Brett Ezell original https://aws.amazon.com/blogs/messaging-and-targeting/upgrade-business-messaging-with-rcs-on-aws/

SMS remains a reliable workhorse for business-to-consumer reach, but it isn’t without its hurdles. Messages from unrecognized numbers are frequently ignored or flagged as spam, and the limitations of plain text can’t provide the interactive experiences modern customers expect. Rich Communication Services (RCS) on AWS End User Messaging addresses these challenges as the next generation of mobile messaging.

Before we get into the technical implementation, it is important to understand what RCS is, why it’s becoming the new standard for business-to-consumer (B2C) communication, and the strategic value it brings to your messaging stack.

The problem with traditional business messaging

Traditional SMS has long been confined to a “narrow lane” of one-directional alerts—think one-time passcodes (OTP) and basic shipment updates. Because these messages arrive from generic-looking short codes or long codes, recipients have no native way to verify the sender’s legitimacy. As a result, users often do the rational thing: they ignore the message or treat it with suspicion.

What is RCS?

RCS is the next-generation messaging protocol developed by the GSM Association (GSMA) to update traditional Short Message Service (SMS) and Multimedia Messaging Service (MMS). Unlike SMS, which relies on the cellular signaling channel, RCS is entirely IP-based, operating over data connectivity (Wi-Fi or mobile data). This shift allows RCS to bring high-resolution media and interactive capabilities directly to the default messaging application.

The core innovation is the RCS Agent—your verified sending identity. Instead of a random number, recipients see your brand name, logo, and a verified checkmark. This shift from “unknown sender” to “verified brand” transforms the recipient’s behavior from passive ignore to active engagement. When customers trust the sender, they stop only reading alerts and start completing workflows, asking questions, and engaging with AI-powered agents built on services like Amazon Bedrock.

The business case for RCS

We can see the future of RCS by looking at markets where over-the-top (OTT) apps like WhatsApp are dominant. In those regions, businesses use messaging for full-lifecycle order management, customer service, and complex scheduling. In markets without that OTT distribution, businesses have been stuck with one-way SMS notifications.

RCS levels this playing field. By bringing a branded, verified identity natively to the default messaging app, it opens up a range of interactive use cases previously reserved for dedicated apps or websites.

Where to start?

When evaluating RCS for your program, we recommend starting with your highest-volume transactional messages. These are often the easiest to migrate because they follow predictable templates. More importantly, they provide the most immediate ROI by maximizing the visibility of your verified identity across your largest customer touchpoints.

To illustrate the business impact across industries:

  • Ecommerce: Order confirmations arriving from a verified brand logo eliminate the “Is this legitimate?” hesitation customers have with SMS from generic numbers. Customers click tracking links confidently because they recognize the sender immediately.
  • Healthcare: Appointment reminders with verified provider identity reduce no-shows and eliminate verification calls. Patients respond more quickly to verified communications and handle appointment management through messaging rather than calling the office.
  • Financial services: Fraud alerts with verified bank identity increase response rates and reduce phishing confusion. Customers see their bank’s logo and verified badge and know the alert is legitimate — enabling faster fraud detection and prevention.

Prerequisites

Before you begin the registration process, make sure that you have the following prerequisites in place:

  • An active AWS account with billing configured.
  • Access to AWS End User Messaging.
  • AWS Identity and Access Management (IAM) permissions to create and manage RCS agents and origination identities.
  • Existing SMS infrastructure to serve as a fallback.
  • A planned timeline that accounts for carrier approval lead times, which vary by country and carrier.
  • A budget for registration and verification fees.

Timeline, planning, and costs

Adopting RCS requires careful planning for both timelines and budgets. Carrier approval timelines vary by country and carrier — approval is not instant. Plan and verify that your processes, such as opt-in consent collection and brand asset preparation, are in place well before your intended launch date.

Registration and usage fees also differ significantly by market. Currently, AWS End User Messaging supports RCS in the United States and Canada, with additional countries planned for future rollout.

  • United States: This market uses a per-segment (160-character) pricing model similar to SMS. It features a higher initial barrier to entry, including a one-time agent setup fee and an annual brand vetting fee.
  • Canada: Canada utilizes a distinct message-based model (“Basic” vs. “Single” messages) rather than segments. Notably, it currently lacks the one-time setup and annual vetting fees found in the US, though a monthly maintenance fee applies globally to all active agents.

Also note that RCS is billed only upon successful delivery, whereas SMS is charged at the time of the request. For the latest rates and a breakdown of carrier-specific content violation fees, see AWS End User Messaging pricing.

Note: You are charged only for successfully delivered messages, not delivery attempts. In the United States, long messages are billed per 160-character segment; however, for the Rest of the World (ROW), messages exceeding 160 characters are billed as a single ‘RCS Single’ message. When automatic fallback occurs, you are typically charged only for the successful SMS delivery. While rare, note that if both the RCS and SMS messages reach the device (dual-delivery), charges for both may apply. For more details, see the RCS billing and pricing model.

RCS and SMS: Better together

RCS works alongside SMS to create a reliable messaging solution with automatic SMS fallback. AWS End User Messaging ensures reliable delivery by intelligently handling three common scenarios where RCS may be unavailable, triggering an automatic fallback to SMS:

  • Carrier-specific availability — Your RCS agent may be approved on some carriers but still pending on others, or a carrier may not have deployed RCS infrastructure yet. AWS detects this upfront using carrier lookup data and automatically routes via SMS so that the message is delivered.
  • Device compatibility — Not all devices support RCS, even if the carrier does. This includes older Android models, devices with RCS disabled, or iPhones running versions earlier than iOS 18. AWS detects this compatibility upfront where possible and automatically routes the message via SMS so that it reaches the recipient.
  • Temporary connectivity — A device may support RCS but lack data connectivity at the moment of delivery (for example, traveling through a tunnel or with data roaming turned off). The device still has cellular coverage for SMS. AWS falls back to SMS so that the message is delivered.
SMS text message from short code 47205 showing a Verizon Call Filter trial activation notice in a dark-themed mobile messaging app, with no sender branding, a generic profile icon, and a "Report Spam" warning at the bottom.

Figure 1: A typical SMS business message often appears from an unrecognizable short code, making it difficult for customers to verify the sender before clicking a link or replying.

When RCS delivery falls back to SMS because of a lack of data connectivity or other availability reasons, AWS uses sticky sending. The service prioritizes the origination number that most recently delivered successfully to that destination—maintaining that preference for 24 hours before retrying RCS. This ensures consistent, recognizable delivery across various connectivity and compatibility scenarios.

Effective phone number management is the foundation for fallback behavior. AWS provides three ways to send messages, each with different fallback behavior:

  • Pool-based sending — AWS selects from identities in a specific pool containing your RCS agent and SMS phone numbers. This is the recommended approach for production deployments. Pools give you precise control over which identities are used while AWS handles automatic routing and fallback.
  • Account-level sending — AWS automatically selects the best identity from your entire account. This is similar to the default behavior in Amazon Simple Notification Service (SNS), where you cannot isolate traffic into specific pools. This approach is ideal for development, testing, or simple deployments where a single identity is used for all messaging use cases within a country.
  • Direct send — You specify an exact RCS agent as the origination identity. The message fails if RCS isn’t available. Use this for testing or when you want to handle fallback yourself.

For production messaging where delivery is critical, use pool-based or account-level sending for reliable delivery. Pools route your fallback SMS messages through consistent, recognizable numbers your customers trust.

RCS vs. SMS at a glance

For a detailed comparison of capabilities, see the following table.

Feature SMS RCS
Character limit 160 characters No practical limit
Media support MMS (compressed) High-resolution images, video, audio
Read receipts No Yes
Typing indicators No Yes
Interactive buttons No Yes
Branded identity Basic (Sender ID) Full (Verified Profile)
Delivery over internet No Yes
Verified RCS business profile for "Go Big or Go Home!" showing a branded hippo logo, purple banner, company tagline, and contact options for call, website, and email in a mobile messaging app.

Figure 2: The final result – A verified brand profile featuring your high-resolution logo, banner image, and custom brand colors—elements that significantly increase trust and click-through rates compared to standard SMS.

The recommended adoption path

Consider a phased approach to RCS adoption that aligns with your operational readiness. First, register your brand and get carrier approval. Next, move your existing SMS use cases to RCS. Finally, after you are comfortable with the channel, test and expand with advanced use cases.

How to register

Brand asset requirements

Before submitting your registration, prepare the following brand assets. Carriers reject assets that don’t meet exact specifications, so verify these requirements before submitting.

Asset Requirements
Logo 224×224 pixels, PNG with transparency, under 50 KB
Banner 1440×448 pixels, PNG or JPEG, under 200 KB
Brand Color Hex format (e.g. #1A73E8), minimum 4.5:1 contrast ratio

Note: A 4.5:1 contrast ratio means your brand color must be at least 4.5 times brighter (or darker) than its background. This threshold meets WCAG 2.1 Level AA standards, ensuring your brand name is legible for users with moderate vision loss or color blindness. To verify compliance, use a Contrast Checker to test your hex code against a solid white background.

Use case selection

Your use case determines what types of messages you can send in production. Select carefully before submitting — the use case does not affect approval timeline, but it does determine your message restrictions and how carriers perceive your traffic.

Use Case What you can send
OTP Authentication codes and security verification only
Transactional Order updates, shipping notifications, account alerts
Promotional Marketing campaigns and offers (requires opt-in consent)
Multi-use Combined transactional and promotional messaging

Why not just choose Multi-use for everything?

While Multi-use offers the most flexibility, it is often subject to stricter carrier scrutiny during the vetting process. Carriers prefer single-purpose agents (like OTP) because they provide a more predictable and trustworthy experience for the recipient. If you have a high-volume OTP use case, registering it separately can help protect your sender reputation from being impacted by the lower engagement rates typically associated with promotional marketing.

Important: Agents must be use-case specific. Sending message types that don’t match your registered use case could result in suspension.

Registration steps

To submit your registration, complete the following steps:

  1. Sign in to the AWS Management Console and open the AWS End User Messaging console.
  2. In the navigation pane, under Configurations, choose RCS agents.
  3. Choose Create RCS Agent. This creates an AWS RCS Agent and then immediately guides you through creating a testing registration in a single workflow.
RCS tester invitation from RBM Tester Management showing interactive "Make me a tester" and "Decline" buttons, user selection, and confirmation message for the "Go Big or Go Home!" RCS agent in a dark-themed mobile messaging app.

Figure 3: Once your agent is created in the AWS console, your registered test devices will receive an invitation like this one. Tapping ‘Make me a tester’ allows you to immediately see your branded content in action.

  1. The next screen shows an introduction to RCS and explains the setup process. Review the information and choose Next to continue.
  2. On the Agent details page, set the following:
    1. Friendly name — A console-only label for your AWS RCS Agent. This is an internal name for your reference (stored as a tag) and is not the name displayed on recipients’ phones. The friendly name is not available through the API.
    2. Deletion protection — (Optional) Enable to prevent accidental deletion of the agent.
    3. Tags — (Optional) Add tags to organize and identify your agent.
  3. In the Brand information section of the same page, enter the following:
    1. Display name — The brand name that recipients see alongside your RCS messages.
    2. Description — A brief description of your brand or business.
    3. Use case — Select the primary use case for your RCS messaging (for example, transactional notifications, marketing, or customer support).
  4. In the Brand assets section of the same page, upload the following:
    1. Logo — 224 × 224 pixels, PNG with transparency, under 50 KB.
    2. Banner image — 1440 × 448 pixels, PNG or JPEG, under 200 KB.
    3. Brand color — A hex color code (for example, #1A73E8) with a minimum contrast ratio of 4.5:1 against a white background.

Important: Some brand assets cannot be changed after the agent is submitted for registration. Prepare your final brand assets before creating the agent. If you want to experiment first, you can quickly create a test agent using this flow, then create a fresh AWS RCS Agent with finalized brand assets later.

  1. On the Compliance keywords page, configure your keywords and auto-response messages.
  2. On the Review page, verify all your settings.
  3. Choose Validate and submit to create the AWS RCS Agent and submit the testing registration.

Testing and production launch phases

Launching RCS follows a distinct path from testing to production:

  1. Testing Registration: The initial guided console flow creates your AWS RCS Agent and a testing agent, or RBM Agent(RCS Business Messaging Agents). This allows you to validate your integration immediately by sending messages to registered test devices without waiting for carrier approval.
  2. Country Launch Registrations: After testing is complete, you must submit separate country launch registrations for each production market.

Carrier review and approval

  • Independent Approval: Each country launch registration undergoes a separate review process by every carrier in that target country.
  • Partial Reach: Approval is per-carrier. You are considered “partially approved” as soon as at least one carrier approves your agent, allowing you to start sending production messages to recipients on that carrier’s network via the SendTextMessage API.
  • Timelines: For both the U.S. and Canada, expect the carrier approval process to take several months. To avoid delays, verify that all registration fields are accurate and, for U.S. launches, provide a clear screen recording demonstrating your intended use case.

Important considerations

Multi-level identity: Think of the AWS RCS Agent as your brand’s unified identity. Under this one resource, you will have multiple RCS for Business IDs: one for your testing agent and separate IDs for each country launch (e.g., one for the US and one for Canada).

Carrier approval is per-carrier, not all-at-once: You do not need to wait for every carrier to approve before you begin sending. As soon as an individual carrier approves your agent, you can reach that carrier’s subscribers.

Sandbox testing: Testing with sandbox agents does not require carrier approval and can begin immediately upon submission. Note that testing messages are charged at standard RCS rates.

Finality of configurations: Brand assets are defined on each specific registration and are final after submission. While minor updates are permitted through supporting documentation, significant structural changes require creating a new agent. Plan your configuration carefully before you submit.

Accuracy matters: Filling out registration forms incorrectly can result in lengthy delays or rejection. Double-check all information before submitting and verify that business documents are current and valid. In this early phase of RCS adoption, carriers have been approving recognizable brands more readily.

Managing costs and usage

Monitor your RCS message volume through Amazon CloudWatch metrics and set up billing alerts to track spending against your SMS baseline. For more information, see AWS End User Messaging pricing.

Conclusion

In this post, we showed you how RCS on AWS End User Messaging solves customer engagement challenges through verified branding, interactive features, and automatic SMS fallback. You get a branded messaging experience with the reliability of SMS built in. Evaluate your current SMS message volume and identify high-priority transactional messages that would benefit from verified branding. Consider migrating these high-impact use cases first to establish your brand presence and improve customer trust.

Get started today

Ready to implement RCS? Here are your next steps:

  • If you’re ready to register: Contact your AWS account team or AWS Support to begin the registration process.
  • If you want to learn more: Review the AWS End User Messaging and RCS documentation.
  • If you’re still evaluating: Start by auditing your current SMS message volume and identifying high-priority transactional messages that would benefit from verified branding.

About the authors

How to use Parquet Column Indexes with Amazon Athena

Post Syndicated from Matt Wong original https://aws.amazon.com/blogs/big-data/how-to-use-parquet-column-indexes-with-amazon-athena/

Amazon Athena recently added support for reading Parquet Column Indexes in Apache Iceberg tables on November 21, 2025. With this optimization, Athena can perform page-level data pruning to skip unnecessary data within Parquet row groups, potentially reducing the amount of data scanned and improving query runtime for queries with selective filters. For data teams, this may help enable faster insights and help reduce costs when analyzing large-scale data lakes.

Data teams building data lakes often choose Apache Iceberg for its ACID transactions, schema evolution, and metadata management capabilities. Athena is a serverless query engine that allows you to query Amazon S3-based data lakes using SQL, and you don’t need to manage infrastructure. Based on the type of data and query logic, Athena can apply multiple query optimizations to improve performance and reduce costs.

In this blog post, we use Athena and Amazon SageMaker Unified Studio to explore Parquet Column Indexes and demonstrate how they can improve Iceberg query performance. We explain what Parquet Column Indexes are, demonstrate their performance benefits, and show you how to use them in your applications.

Overview of Parquet Column Indexes

Parquet Column Indexes store metadata that query engines can use to skip irrelevant data with greater precision than row group statistics alone. To understand how they work, consider how data is structured within Parquet files and how engines like Athena process them.

Parquet files organize data hierarchically by dividing data into row groups (typically 128-512 MB each) and further subdividing them into pages (typically 1 MB each). Traditionally, Parquet maintains metadata on the contents of each row group level in the form of min/max statistics, allowing engines like Athena to skip row groups that don’t satisfy query predicates. Although this approach reduces the bytes scanned and query runtime, it has limitations. If even a single page within a row group overlaps with the values you are searching for, Athena scans all pages within the row group.

Parquet Column Indexes help address this problem by storing page-level min/max statistics in the Parquet file footer. Row group statistics provide coarse-grained filtering, but Parquet Column Indexes enable finer-grained filtering by allowing query engines like Athena to skip individual pages within a row group. Consider a Parquet file with a single row group containing 5 pages for a column. The row group has min/max statistics of (1, 20), and each page for that column has the following min/max statistics.

row-group-0: min=1, max=20
    page-0: min=1, max=10
    page-1: min=1, max=10
    page-2: min=5, max=15
    page-3: min=6, max=16
    page-4: min=10, max=20

When Athena runs a query filtering for values equal to 2, it first checks the row group statistics and confirms that 2 falls within the range (1, 20). Athena will then plan to scan the pages within that row group. Without Parquet Column Indexes, Athena scans each of the 5 pages in the row group. With Parquet Column Indexes, Athena examines the page-level statistics and determines that only page-0 and page-1 need to be read, skipping the remaining 3 pages.

How to use Parquet Column Indexes with Athena

Athena uses Parquet Column Indexes based on table type:

  • Amazon S3 Tables: Athena automatically uses Parquet Column Indexes by default when they are present.
  • Iceberg tables in S3 general purpose buckets: Athena does not use Parquet Column Indexes by default. To allow Athena to use Parquet Column Indexes, add an AWS Glue table property named use_iceberg_parquet_column_index and set it to true. Use the AWS Glue console or AWS Glue UpdateTable API to perform these actions.

Read more about how to use this feature in Use Parquet column indexing.

Measuring Athena performance gains when using Parquet Column Indexes

Now that we understand what Parquet Column Indexes are, we’ll demonstrate the performance benefits of using Parquet Column Indexes by analyzing the catalog_sales table from a 3TB TPC-DS dataset. This table contains ecommerce transaction data including order dates, sales amounts, customer IDs, and product information. This dataset is a good proxy for the types of business analysis that you might perform on your own data, such as identifying sales trends, analyzing customer purchasing patterns, and calculating revenue metrics. We compare query execution statistics with and without Parquet Column Indexes to quantify the performance improvement.

Prerequisites

Before you begin, you must have the following resources:

  1. A SageMaker Unified Studio IAM-based domain.
  2. An Execution IAM Role configured within the SageMaker Unified Studio IAM-based domain with access to S3, AWS Glue Data Catalog, and Athena.
  3. An S3 bucket in your account to store Iceberg table data and Athena query results.

Create catalog_sales Iceberg table

Complete the following steps using SageMaker Unified Studio notebooks. There, you can use SageMaker Unified Studio’s multi-dialect notebook functionality to work with your data using the Athena SQL and Spark engines. To create a catalog_sales Iceberg table in your account, follow these steps:

  1. Navigate to Amazon SageMaker in the AWS Management Console and choose Open under Get started with Amazon SageMaker Unified Studio.
  2. From the side navigation, select Notebooks and choose Create Notebook. The subsequent steps in this post will execute scripts in this notebook.
  3. Create a new SQL cell in the notebook and set the connection type to Athena (Spark). Execute the following query to create a database for the tables in this post.
    CREATE DATABASE parquet_column_index_blog;

  4. Create a new SQL cell in the notebook and verify the connection type is Athena (Spark). Execute the following query to create a Hive table pointing to the location of the TPC-DS catalog_sales table data at the public S3 bucket.
    CREATE TABLE IF NOT EXISTS parquet_column_index_blog.catalog_sales_hive (
    	  cs_sold_time_sk int,
    	  cs_ship_date_sk int,
    	  cs_bill_customer_sk int,
    	  cs_bill_cdemo_sk int,
    	  cs_bill_hdemo_sk int,
    	  cs_bill_addr_sk int,
    	  cs_ship_customer_sk int,
    	  cs_ship_cdemo_sk int,
    	  cs_ship_hdemo_sk int,
    	  cs_ship_addr_sk int,
    	  cs_call_center_sk int,
    	  cs_catalog_page_sk int,
    	  cs_ship_mode_sk int,
    	  cs_warehouse_sk int,
    	  cs_item_sk int,
    	  cs_promo_sk int,
    	  cs_order_number bigint,
    	  cs_quantity int,
    	  cs_wholesale_cost decimal(7, 2),
    	  cs_list_price decimal(7, 2),
    	  cs_sales_price decimal(7, 2),
    	  cs_ext_discount_amt decimal(7, 2),
    	  cs_ext_sales_price decimal(7, 2),
    	  cs_ext_wholesale_cost decimal(7, 2),
    	  cs_ext_list_price decimal(7, 2),
    	  cs_ext_tax decimal(7, 2),
    	  cs_coupon_amt decimal(7, 2),
    	  cs_ext_ship_cost decimal(7, 2),
    	  cs_net_paid decimal(7, 2),
    	  cs_net_paid_inc_tax decimal(7, 2),
    	  cs_net_paid_inc_ship decimal(7, 2),
    	  cs_net_paid_inc_ship_tax decimal(7, 2),
    	  cs_net_profit decimal(7, 2))
    	USING parquet
    	PARTITIONED BY (cs_sold_date_sk int)
    	LOCATION 's3://blogpost-sparkoneks-us-east-1/blog/BLOG_TPCDS-TEST-3T-partitioned/catalog_sales/'
    	TBLPROPERTIES (
    	  'parquet.compression'='SNAPPY'
    	);

  5. Create a new SQL cell in the notebook and verify the connection type is Athena (Spark). Execute the following query to add the Hive partitions to the AWS Glue metadata.
    MSCK REPAIR TABLE parquet_column_index_blog.catalog_sales_hive;

  6. Create a new SQL cell in the notebook and verify the connection type is Athena (Spark). Replace s3://amzn-s3-demo-bucket/athena_parquet_column_index_blog/catalog_sales/ with the S3 URI where you want to store your Iceberg table data, then execute the following query to create the catalog_sales Iceberg table from the Hive table.
    CREATE TABLE parquet_column_index_blog.catalog_sales
    	USING iceberg
    	PARTITIONED BY (cs_sold_date_sk)
    	LOCATION 's3://amzn-s3-demo-bucket/athena_parquet_column_index_blog/catalog_sales/'
    	AS
    	SELECT * FROM parquet_column_index_blog.catalog_sales_hive;

  7. Create a new SQL cell in the notebook and verify the connection type is Athena (Spark). Execute the following query to delete the catalog_sales_hive table, which was only needed to create the catalog_sales Iceberg table.
    DROP TABLE parquet_column_index_blog.catalog_sales_hive;

Run an Athena query without Parquet Column Indexes

After creating the catalog_sales Iceberg table in the preceding steps, we run a simple query that analyzes shipping delays of the top 10 most ordered items. This type of analysis could be critical for ecommerce and retail operations. By identifying which popular items experience the greatest delays, fulfillment teams can focus resources where they matter most. For example, you can adjust inventory placement, change warehouse assignments, or address carrier issues. Additionally, popular items with significant shipping delays are more likely to result in order cancellations or returns, so proactively identifying these issues helps protect revenue.

SELECT cs_item_sk,
    SUM(cs_quantity) as total_orders,
    AVG(cs_ship_date_sk - cs_sold_date_sk) as avg_ship_delay_days,
    MIN(cs_ship_date_sk - cs_sold_date_sk) as min_ship_delay,
    MAX(cs_ship_date_sk - cs_sold_date_sk) as max_ship_delay,
    SUM(
        CASE
            WHEN cs_ship_date_sk - cs_sold_date_sk > 7 THEN 1 ELSE 0
        END
    ) as late_shipments,
    SUM(
        CASE
            WHEN cs_ship_date_sk - cs_sold_date_sk > 7 THEN 1 ELSE 0
        END
    ) * 100.0 / COUNT(*) as late_shipment_pct,
    AVG(cs_ext_ship_cost) as avg_shipping_cost
FROM parquet_column_index_blog.catalog_sales
WHERE cs_item_sk IN (
        SELECT cs_item_sk
        FROM parquet_column_index_blog.catalog_sales
        WHERE cs_item_sk IS NOT NULL
        GROUP BY cs_item_sk
        ORDER BY SUM(cs_quantity) DESC
        LIMIT 10
    )
    AND cs_ship_date_sk IS NOT NULL
    AND cs_sold_date_sk IS NOT NULL
GROUP BY cs_item_sk
ORDER BY avg_ship_delay_days DESC;

Additionally, this query is a good candidate for demonstrating the effectiveness of using Parquet Column Indexes because it has a selective filter predicate on a single column cs_item_sk. When Athena executes this query, it first identifies row groups whose min/max ranges overlap with the top 10 most ordered items. Without using Parquet Column Indexes, Athena has to scan every page of data within those matched row groups. However, when using Parquet Column Indexes, Athena can prune data further by skipping individual pages within those row groups whose min/max ranges do not overlap with the ids. Complete the following steps to establish baseline query performance when Athena does not use Parquet Column Indexes during the query.

  1. Create a new Python cell in the notebook. Replace s3://amzn-s3-demo-bucket/athena_parquet_column_index_blog/query_results/ with the S3 URI where you want to store your Athena query results, then execute the following script. Note the runtime and bytes scanned that will be printed. The script will run the query five times with query result reuse disabled and chooses the minimum runtime and the corresponding bytes scanned among those iterations. See our numbers in the Run Athena query with Parquet Column Indexes section.
    import boto3
    import time
    
    # Configuration
    DATABASE = "parquet_column_index_blog"
    OUTPUT_LOCATION = "s3://amzn-s3-demo-bucket/athena_parquet_column_index_blog/query_results/"
    
    def run_athena_query(query: str, database: str, output_location: str):
        athena_client = boto3.client('athena')
        
        response = athena_client.start_query_execution(
            QueryString=query,
            QueryExecutionContext={'Database': database},
            ResultConfiguration={'OutputLocation': output_location}
        )
        
        query_execution_id = response['QueryExecutionId']
        
        while True:
            result = athena_client.get_query_execution(QueryExecutionId=query_execution_id)
            state = result['QueryExecution']['Status']['State']
            
            if state in ['SUCCEEDED', 'FAILED', 'CANCELLED']:
                break
            
            time.sleep(5)
        
        if state != 'SUCCEEDED':
            raise Exception(f"Query failed with state: {state}")
        
        stats = result['QueryExecution']['Statistics']
        
        return {
            'execution_time_sec': stats['EngineExecutionTimeInMillis'] / 1000,
            'data_scanned_gb': stats['DataScannedInBytes'] / (1024 ** 3)
        }
    
    
    def benchmark_query(query: str, database: str, output_location: str, num_runs: int = 5):
        results = []
        
        for i in range(num_runs):
            stats = run_athena_query(query, database, output_location)
            results.append(stats)
        
        best_run = min(results, key=lambda r: r['execution_time_sec'])
        
        execution_time = round(best_run['execution_time_sec'], 1)
        data_scanned = round(best_run['data_scanned_gb'], 1)
        
        print(f"Execution time: {execution_time} sec")
        print(f"Data scanned: {data_scanned} GB")
    
    
    QUERY = """
    SELECT cs_item_sk,
        SUM(cs_quantity) as total_orders,
        AVG(cs_ship_date_sk - cs_sold_date_sk) as avg_ship_delay_days,
        MIN(cs_ship_date_sk - cs_sold_date_sk) as min_ship_delay,
        MAX(cs_ship_date_sk - cs_sold_date_sk) as max_ship_delay,
        SUM(
            CASE
                WHEN cs_ship_date_sk - cs_sold_date_sk > 7 THEN 1 ELSE 0
            END
        ) as late_shipments,
        SUM(
            CASE
                WHEN cs_ship_date_sk - cs_sold_date_sk > 7 THEN 1 ELSE 0
            END
        ) * 100.0 / COUNT(*) as late_shipment_pct,
        AVG(cs_ext_ship_cost) as avg_shipping_cost
    FROM parquet_column_index_blog.catalog_sales
    WHERE cs_item_sk IN (
            SELECT cs_item_sk
            FROM parquet_column_index_blog.catalog_sales
            WHERE cs_item_sk IS NOT NULL
            GROUP BY cs_item_sk
            ORDER BY SUM(cs_quantity) DESC
            LIMIT 10
        )
        AND cs_ship_date_sk IS NOT NULL
        AND cs_sold_date_sk IS NOT NULL
    GROUP BY cs_item_sk
    ORDER BY avg_ship_delay_days DESC;
    """
    
    # Run benchmark
    benchmark_query(QUERY, DATABASE, OUTPUT_LOCATION, num_runs=5)

Sort the catalog_sales table

Before rerunning the query with Athena using Parquet Column Indexes, you need to sort the catalog_sales table by the cs_item_sk column. In the preceding query, there is a dynamic filter as a subquery on the cs_item_sk column:

cs_item_sk IN (
        SELECT cs_item_sk
        FROM parquet_column_index_blog.catalog_sales
        WHERE cs_item_sk IS NOT NULL
        GROUP BY cs_item_sk
        ORDER BY SUM(cs_quantity) DESC
        LIMIT 10
    )

When executing this query, Athena pushes down the filter predicate to the data source level, fetching only rows that match the top 10 most ordered items. To maximize page pruning with Parquet Column Indexes, rows with the same cs_item_sk values should be stored near each other in the Parquet file. Without sorting, matching values could be scattered across many pages, forcing Athena to read more data. Sorting the table by cs_item_sk clusters similar values together, enabling Athena to read fewer pages.

Let’s examine the Parquet Column Indexes in one of the Parquet files to understand how the data in the catalog_sales table is currently organized. First, download the Parquet file from the cs_sold_date_sk = 2450815 partition and install the open-source parquet-cli tool on your local machine. Replace <local-path-to-parquet-file> with the path to the downloaded Parquet file, then run the following command on your local machine:

parquet column-index <local-path-to-parquet-file>

This displays Parquet Column Indexes for all columns. For brevity, only the first 11 pages of the cs_item_sk column from the first row group are shown in the following example:

row-group 0:
column index for column cs_item_sk:
Boundary order: UNORDERED
         null_count  min  max
page-0            0    4  359989
page-1            0    2  359996
page-2            0   10  359995
page-3            0   13  359996
page-4            0   22  359989
page-5            0   25  359984
page-6            0   13  359989
page-7            0   56  359990
page-8            0   14  359984
page-9            0    7  359978
page-10           0    1  359998

Notice that nearly every page contains a wide range of values. This overlap means Athena cannot eliminate pages when filtering with Parquet Column Indexes on cs_item_sk. For example, searching for cs_item_sk = 100 requires scanning each of the 11 pages because the value 100 falls within every page’s min/max range. With this overlap, enabling Athena to use Parquet Column Indexes would provide no performance benefit. Sorting the data by cs_item_sk eliminates this overlap, creating distinct, non-overlapping ranges for each page. To make Parquet Column Indexes more effective, sort the table by completing the following step:

  1. Create a new SQL cell in the notebook and verify the connection type is Athena (Spark). Execute the query to sort the cs_item_sk column values of the catalog_sales table in ascending order and to put all the null values in the last few Parquet pages. New Iceberg data files will be generated from this query.
    CALL spark_catalog.system.rewrite_data_files(
    table => 'parquet_column_index_blog.catalog_sales', 
    strategy => 'sort', 
    sort_order => 'cs_item_sk ASC NULLS LAST', 
    options => map('target-file-size-bytes', '1073741824', 
    'rewrite-all', 'true', 'max-concurrent-file-group-rewrites', '200'));

Running the parquet column-index command on the sorted data file from the cs_sold_date_sk = 2450815 partition shows that the Parquet Column Indexes are now sorted and have non-overlapping ranges. The first 11 pages of the cs_item_sk column from the first row group are shown in the following example:

row-group 0:
column index for column cs_item_sk:
Boundary order: ASCENDING
         null_count  min    max
page-0           0      1   5282
page-1           0   5282  10556
page-2           0  10556  15842
page-3           0  15842  21154
page-4           0  21154  26434
page-5           0  26434  31669
page-6           0  31669  36916
page-7           0  36916  42205
page-8           0  42205  47528
page-9           0  47528  52808
page-10          0  52808  58189

Now when searching for cs_item_sk = 100, Athena only needs to read page-0, skipping the remaining 10 pages entirely.

Run Athena query with Parquet Column Indexes

Now that the data is sorted to eliminate overlapping pages within the row groups for the cs_item_sk column, we run two experiments on the sorted data. The first measures the impact of sorting alone, and the second measures the combined effect of sorting with Parquet Column Indexes.

  1. Create a new Python cell in the notebook. Execute the same script in the section Run Athena query without Parquet Column Indexes and take note of the query runtime and bytes scanned results. This measures the performance of querying sorted data without using Parquet Column Indexes.
  2. Create a new Python cell in the notebook. Execute the following Python script to set the use_iceberg_parquet_column_index table property to true for the catalog_sales table in the AWS Glue Data Catalog.
    import boto3
    
    def add_iceberg_parquet_column_index(database_name: str, table_name: str):
        glue_client = boto3.client('glue')
        
        # Get current table definition
        response = glue_client.get_table(DatabaseName=database_name, Name=table_name)
        table = response['Table']
        
        # Build TableInput with only allowed fields
        table_input = {'Name': table['Name']}
        
        allowed_fields = [
            'Description', 'Owner', 'LastAccessTime', 'LastAnalyzedTime',
            'Retention', 'StorageDescriptor', 'PartitionKeys', 'ViewOriginalText',
            'ViewExpandedText', 'TableType', 'Parameters', 'TargetTable'
        ]
        
        for field in allowed_fields:
            if field in table:
                table_input[field] = table[field]
        
        # Add the property
        if 'Parameters' not in table_input:
            table_input['Parameters'] = {}
        table_input['Parameters']['use_iceberg_parquet_column_index'] = 'true'
        
        # Update the table
        glue_client.update_table(DatabaseName=database_name, TableInput=table_input)
    
    # Usage
    add_iceberg_parquet_column_index("parquet_column_index_blog", "catalog_sales")

  3. Create a new Python cell in the notebook. Execute the same script in the section Run Athena query without Parquet Column Indexes and take note of the query runtime and bytes scanned results. This measures the performance of querying sorted data using Parquet Column Indexes.

Athena query time and bytes scanned improvement

The following table summarizes the results from each experiment. The percentage improvements for the sorted experiments are measured against the unsorted baseline.

Experiment Runtime (sec) Bytes Scanned (GB)
Unsorted without Parquet Column Indexes 20.6 45.2
Sorted without Parquet Column Indexes 15.4 (25.2% faster) 27.8 (38.5% fewer bytes)
Sorted with Parquet Column Indexes 10.3 (50.0% faster) 13.0 (71.2% fewer bytes)

Recommendations

To maximize Athena’s ability to use Parquet Column Indexes and achieve optimal query performance, we recommend the following.

  1. Sort data by frequently filtered columns. This allows Athena to efficiently read Parquet Column Indexes and skip irrelevant pages, potentially reducing scan time. When data is sorted by a filter column, similar values are clustered together within pages. Because Parquet Column Indexes store min/max values for each page, Athena can quickly determine which pages contain matching values and skip the rest.
  2. Sort data by high-cardinality columns. This creates distinct value ranges between pages, maximizing the opportunity for Athena to skip pages during query execution. High-cardinality (many distinct values) columns produce non-overlapping min/max ranges across pages, allowing Athena to more effectively filter out irrelevant pages. In contrast, low-cardinality columns such as boolean or status fields result in overlapping ranges across many pages, reducing the number of skipped pages.

Clean up

When you have finished the steps in this post, complete the following cleanup actions to avoid incurring ongoing charges:

  1. Create a new SQL cell in the notebook and set the connection type to Athena (Spark). Execute the following command to drop the parquet_column_index_blog database and the catalog_sales table.
    DROP DATABASE parquet_column_index_blog CASCADE;

  2. Delete the Iceberg table data and the Athena query results from your S3 bucket.
  3. Delete the SageMaker Unified Studio IAM-based domain if it is no longer needed.

Conclusion

In this post, we showed you how Athena uses Parquet Column Indexes to speed up queries and reduce the number of bytes scanned. By using Parquet Column Indexes, Athena can skip irrelevant data pages to improve query performance, especially for queries with selective filters on sorted data. Refer to Optimize Iceberg tables to learn more about this feature and try it out on your own queries.


About the Author

Portrait photograph of a young Asian male in his twenties wearing a black t-shirt against a neutral gray background

Matt Wong

Matt is a Software Development Engineer on Amazon Athena. He has worked on several projects within the Amazon Athena Datalake and Storage team and is continuing to build out more Athena features. Outside of work, Matthew likes to spend time juggling, biking, and running with family and friends.

Implementing Kerberos authentication for Apache Spark jobs on Amazon EMR on EKS to access a Kerberos-enabled Hive Metastore

Post Syndicated from Krishna Kumar Venkateswaran original https://aws.amazon.com/blogs/big-data/implementing-kerberos-authentication-for-apache-spark-jobs-on-amazon-emr-on-eks-to-access-a-kerberos-enabled-hive-metastore/

Many organizations run their Apache Spark analytics platforms on Amazon EMR on Amazon Elastic Compute Cloud (Amazon EC2), using Kerberos authentication to secure connectivity between Spark jobs and a centralized shared Apache Hive Metastore (HMS). With Amazon EMR on Amazon EKS, they gained a new option for running Spark jobs with the benefits of Kubernetes-based container orchestration, improved resource utilization, and faster job startup times. However, an HMS deployment supports only one authentication mechanism at a time. This means that they must configure Kerberos authentication for their Spark jobs on Amazon EMR on EKS to connect to the existing Kerberos-enabled HMS.

In this post, we show how to configure Kerberos authentication for Spark jobs on Amazon EMR on EKS, authenticating against a Kerberos-enabled HMS so you can run both Amazon EMR on EC2 and Amazon EMR on EKS workloads against a single, secure HMS deployment.

Overview of solution

Consider an enterprise data platform team that’s been running Spark jobs on Amazon EMR on EC2 for several years. Their architecture includes a Kerberos-enabled standalone HMS that serves as the centralized data catalog, with Microsoft Active Directory functioning as the Key Distribution Center (KDC). As the team evaluates Amazon EMR on EKS for new workloads, their existing HMS must continue serving Amazon EMR on EC2, with both authenticating through the same Kerberos infrastructure. To address this, the platform team must configure their Spark jobs running on Amazon EMR on EKS to authenticate with the same KDC. This is so they can obtain valid Kerberos tickets and establish authenticated connections to the HMS while maintaining a unified security posture across their data platform.

Architecture diagram showing two VPCs connected via VPC peering: the Active Directory VPC contains Microsoft Active Directory serving as the Kerberos Key Distribution Center (KDC) with ports 88 (Kerberos) and 749 (Admin). The Amazon EKS VPC contains two namespaces — the emr namespace runs Apache Spark jobs (each with a driver pod and executor pods) configured with krb5.conf, jaas.conf, and keytab files using a spark/analytics-team@CORP.KERBEROS principal; the hive-metastore namespace runs Hive Metastore pods (with deployment, replica set, and HPA) configured with Kerberos artifacts and the hive/hive-metastore@CORP.KERBEROS principal. Spark driver pods connect to the Hive Metastore service, which is backed by Amazon Aurora PostgreSQL for metadata storage and Amazon S3 for data storage. AWS Secrets Manager stores Kerberos keytabs and database credentials retrieved during deployment. Users submit Spark jobs via AWS Systems Manager Session Manager.

Scope of Kerberos in this solution

Kerberos authentication in this solution secures the connection between Spark jobs and the HMS. Other components in the architecture use AWS and Kubernetes security mechanisms instead.

Solution architecture

Our solution implements Kerberos authentication to secure the connection between Spark jobs and the HMS. The architecture spans two Amazon Virtual Private Clouds (Amazon VPCs) connected using VPC peering, with distinct components handling identity management, compute, and metadata services.

Identity and Authentication layer

A self-managed Microsoft Active Directory Domain Controller is deployed in a dedicated VPC and serves as the KDC for Kerberos authentication. The Active Directory server hosts service principals for both the HMS service and Spark jobs. This separate VPC deployment mirrors real-world enterprise architectures where Active Directory is typically managed by identity teams in their own network boundary, whether on-premises or in AWS.

Data Platform layer

The data platform components reside in a separate VPC and includes an EKS cluster that hosts both the HMS service and Amazon EMR on EKS based Spark jobs persisting data in an Amazon Simple Storage Service (Amazon S3) bucket.

Hive Metastore service

The HMS is deployed in the EKS hive-metastore namespace and simulates a pre-existing, standalone Kerberos-enabled HMS, a common enterprise pattern where HMS is managed independently of any data processing platform. You can learn more about other enterprise design patterns in the post Design patterns for implementing Hive Metastore for Amazon EMR or EKS. The HMS service authenticates with the KDC using its service principal and keytab mounted from a Kubernetes secret.

Apache Spark Execution layer

Apache Spark jobs are deployed using the Spark Operator on EKS. The Spark driver and executor pods are configured with Kerberos credentials through mounted ConfigMaps containing krb5.conf and jaas.conf, along with keytab files from Kubernetes secrets. When a Spark job must access Hive tables, the driver authenticates with the KDC and establishes a secure Simple Authentication and Security Layer (SASL) connection to the HMS.

Authentication flow

The HMS runs as a long-running Kubernetes service that must be deployed and authenticated before Spark jobs can connect.

During HMS deployment:

  1. HMS pod validates its Kerberos configuration. krb5.conf and jaas.conf are mounted from ConfigMaps
  2. Service authenticates with KDC using its principal hive/hive-metastore-svc.hive-metastore.svc.cluster.local@CORP.KERBEROS
  3. keytab is mounted from Kubernetes secret for credential access
  4. Secure Thrift endpoint is established on port 9083 with SASL authentication enabled

When a Spark job must interact with the HMS:

  1. Spark job submission:
    1. User submits Spark job through Spark Operator
    2. Driver and executor pods are created with Kerberos configuration mounted as volumes
    3. krb5.conf ConfigMap provides KDC connection details including realm and server addresses
    4. jaas.conf ConfigMap specifies a login module configuration with keytab path and principal
    5. Keytab secret contains encrypted credentials for Spark service principal spark/[email protected]
  2. Authentication and connection:
    1. Spark driver authenticates with KDC using its principal and keytab to obtain a Ticket Granting Ticket (TGT)
    2. When connecting to HMS, Spark requests a service ticket from the KDC for the HMS principal hive/hive-metastore-svc.hive-metastore.svc.cluster.local@CORP.KERBEROS
    3. KDC issues a service ticket encrypted with HMS’s secret key
    4. Spark presents this service TGT to HMS over the Thrift connection on port 9083
    5. HMS decrypts the ticket using its keytab, verifies Spark’s identity, and establishes the authenticated SASL session
    6. Executor pods use the same configuration for authenticated operations
  3. Data access:
    1. Authenticated Spark job queries HMS for table metadata
    2. HMS validates Kerberos tickets before serving metadata requests
    3. Spark accesses underlying data in Amazon S3 using IRSA

Sequence diagram illustrating the Kerberos authentication flow between a Spark job and the Hive Metastore. The flow proceeds in five phases: (1) Job Submission — a Data Engineer submits a SparkApplication via kubectl, and the Spark Operator creates a driver pod with krb5.conf, jaas.conf, and keytab mounted. (2) Kerberos Authentication — the Spark driver loads its keytab for the spark/analytics-team@CORP.KERBEROS principal and sends an AS-REQ to the Active Directory KDC, which validates the credentials and returns a TGT (Ticket Granting Ticket). (3) Service Ticket Request — the Spark driver sends a TGS-REQ to the KDC requesting a service ticket for the Hive Metastore principal, and the KDC returns a service ticket encrypted with the HMS key. (4) Authenticated Connection — the Spark driver connects to the Hive Metastore over Thrift (port 9083) using SASL with the service ticket; HMS decrypts the ticket using its own keytab, verifies the Spark identity, and establishes an authenticated session. (5) Data Operations — the Spark driver queries table metadata from HMS (backed by Aurora PostgreSQL) and reads/writes table data directly from Amazon S3 using IRSA credentials.

Implementation workflow

The implementation involves three key stakeholders working together to establish the Kerberos-enabled communication:

Microsoft Active Directory Administrator

The Active Directory Administrator creates service accounts that are used for HMS and Spark jobs. This involves setting up the service principal names using the setspn utility and generating keytab files using ktpass for secure credential storage. The administrator configures the appropriate Active Directory permissions and Kerberos AES256 encryption type. Finally, the keytab files are uploaded to AWS Secrets Manager for secure distribution to Kubernetes workloads.

Data Platform Team

The platform team handles the Amazon EMR on EKS and Kubernetes configurations. They retrieve keytabs from Secrets Manager and create Kubernetes secrets for the workloads. They configure Helm charts for HMS deployment with Kerberos settings and set up ConfigMaps for krb5.conf, jaas.conf, and core-site.xml.

Data Engineering Operations

Data engineers submit jobs using the configured service account with Kerberos authentication. They monitor job execution and verify authenticated access to HMS.

Deploy the solution

In the remainder of this post, you will explore the implementation details for this solution. You can find the sample code in the AWS Samples GitHub repository. For additional details, including verification steps for each deployment stage, refer to the README in the repository.

Prerequisites

Before you deploy this solution, make sure that the following prerequisites are in place:

Clone the repository and set up environment variables

Clone the repository to your local machine and set the two environment variables. Replace <AWS_REGION> with the AWS Region where you want to deploy these resources.

# Clone the Git repository
git clone https://github.com/aws-samples/sample-emr-eks-spark-kerberos-hms.git
cd sample-emr-eks-spark-kerberos-hms

# Set environment variables
export REPO_DIR=$(pwd)
export AWS_REGION=<AWS_REGION>

Setup Microsoft Active Directory infrastructure

In this section, we deploy a self-managed Microsoft Active Directory with KDC on a Windows Server EC2 instance into a dedicated VPC. This is an intentionally minimal implementation highlighting only the key components required for this blog post.

cd ${REPO_DIR}/microsoft-ad
./setup.sh

Setup EKS infrastructure

This section provisions the Amazon EMR on EKS infrastructure stack, including VPC, EKS cluster, Amazon Aurora PostgreSQL database, Amazon Elastic Container Registry (Amazon ECR), Amazon S3, Amazon EMR on EKS virtual clusters and the Spark Operator. Run the following script.

cd ${REPO_DIR}/data-infra
./setup.sh

Set up VPC peering

This section establishes network connectivity between the Active Directory VPC and EKS VPC for Kerberos authentication. Run the following script:

cd ${REPO_DIR}/vpc-peering
./setup.sh

Deploy Hive Metastore with Kerberos authentication

This section deploys a Kerberos-enabled HMS service on the EKS cluster. Complete the following steps:

  1. Create Kerberos Service Principal for HMS service
cd ${REPO_DIR}/microsoft-ad/
# Create HMS service principal
./manage-ad-service-principals.sh create hive "hive/hive-metastore-svc.hive-metastore.svc.cluster.local"
# Verify the service principal was created
./manage-ad-service-principals.sh list
  1. Deploy HMS service with Kerberos authentication
cd ${REPO_DIR}/hive-metastore
./deploy.sh

Set up Amazon EMR on Amazon EKS with Kerberos authentication

This section configures Spark jobs to authenticate with Kerberos-enabled HMS. This involves creating service principles for Spark jobs and generating the necessary configuration files. Complete the following steps:

  1. Create Service Principal for Spark jobs
cd ${REPO_DIR}/microsoft-ad/
# Create Spark service principal
./manage-ad-service-principals.sh create spark "spark/analytics-team"
# Verify the service principal was created
./manage-ad-service-principals.sh list
  1. Generate Kerberos configurations for Spark jobs
cd ${REPO_DIR}/spark-jobs/
./generate-spark-configs.sh --principal "spark/[email protected]" --namespace emr

Submit Spark jobs

This section verifies Kerberos authentication by running a Spark job that connects to the Kerberized HMS. Complete the following steps:

  1. Submit the test Spark job
cd ${REPO_DIR}/spark-jobs
kubectl apply -f spark-job.yaml
  1. Monitor job execution
# Watch the SparkApplication status
kubectl get sparkapplications -n emr -w
# Check pod status
kubectl get pods -n emr | grep "spark-kerberos"
  1. Verify Kerberos authentication and HMS connection
# Check Spark driver logs for successful authentication
kubectl logs spark-kerberos-job-driver -n emr

The logs should confirm successful authentication, along with a listing of sample databases and tables.

Understanding Kerberos configuration

The HMS requires specific configuration parameters to enable Kerberos authentication, applied through the previously mentioned steps. The key configurations are outlined in the following section.

HMS configuration (metastore-site.xml)

The following configurations are added to metastore-site.xml file.

Setting Value Purpose
hive.metastore.sasl.enabled true Enable SASL authentication
hive.metastore.kerberos.principal hive/hive-metastore-svc.hive-metastore.svc.cluster.local@CORP.KERBEROS HMS service principal
hive.metastore.kerberos.keytab.file /etc/security/keytab/hive.keytab Keytab path

Hadoop security (core-site.xml)

The following configurations are added to the core-site.xml file.

Setting Value
hadoop.security.authentication kerberos
hadoop.security.authorization true

Spark configuration

Setting Value Purpose
spark.security.credentials.kerberos.enabled true Enable Kerberos for Spark
spark.hadoop.hive.metastore.sasl.enabled true SASL for HMS connection
spark.kerberos.principal spark/[email protected] Spark service principal
spark.kerberos.keytab local:///etc/security/keytab/analytics-team.keytab Keytab path

Shared Kerberos files

Both HMS and Spark pods mount two common Kerberos configuration files: krb5.conf and jaas.conf, using ConfigMaps and Kubernetes secrets. The krb5.conf file is identical across both services and defines how each component connects to the KDC. The jaas.conf file follows the same structure but differs in the principal and keytab path for each service.

  1. krb5 Configuration
[libdefaults]
	default_realm = CORP.KERBEROS
	dns_lookup_realm = false
	dns_lookup_kdc = false
	ticket_lifetime = 24h
	forwardable = true
	udp_preference_limit = 1
	default_tkt_enctypes = aes256-cts-hmac-sha1-96 aes128-cts-hmac-sha1-96
	default_tgs_enctypes = aes256-cts-hmac-sha1-96 aes128-cts-hmac-sha1-96
	permitted_enctypes = aes256-cts-hmac-sha1-96 aes128-cts-hmac-sha1-96

[realms]
	CORP.KERBEROS = {
		kdc = <ad-server-ip>
		admin_server = <ad-server-ip>
	}

[domain_realm]
	.corp.kerberos = CORP.KERBEROS
	corp.kerberos = CORP.KERBEROS

For more information, see the online documentation for krb5.conf.

  1. JAAS configuration
Client {
 com.sun.security.auth.module.Krb5LoginModule required
 useKeyTab=true
 keyTab="/etc/security/keytab/hive.keytab"
 principal="hive/hive-metastore-svc.hive-metastore.svc.cluster.local@CORP.KERBEROS"
 useTicketCache=false
 storeKey=true
 debug=false;
};

Additional security considerations

This post focuses on core Kerberos authentication mechanics between Spark and HMS. We recommend two additional security hardening steps based on your organization’s security posture and compliance requirements.

Protecting Keytabs at Rest with AWS KMS Envelope Encryption

Keytabs stored as Kubernetes Secrets are only base64-encoded by default, not encrypted at rest. We recommend enabling EKS envelope encryption using an AWS Key Management Service (AWS KMS) customer managed key. With envelope encryption, secret data is encrypted with a Data Encryption Key (DEK), which is encrypted by your customer managed key. This protects keytab content even if the etcd datastore is compromised. To enable this on an existing EKS cluster:

aws eks associate-encryption-config \
  --cluster-name <your-cluster> \
  --encryption-config '[{"resources":["secrets"],"provider":{"keyArn":"arn:aws:kms:<region>:<account-id>:key/<key-id>"}}]'

Refer to the Amazon EKS documentation on envelope encryption for full setup guidance.

Encrypting the Thrift Data Channel with TLS

SASL with Kerberos provides mutual authentication but doesn’t automatically encrypt data over the Thrift connection. Many deployments default to auth QoP, leaving the data channel unencrypted. We recommend either:

  • Set SASL QoP to auth-conf — enables SASL-layer encryption using Kerberos session keys
  • Layer TLS over Thrift (preferred) — enables transport-level encryption using modern cipher suites

Enabling TLS on HiveServer2 / Hive Metastore Thrift:

<property>
  <name>hive.server2.use.SSL</name>
  <value>true</value>
</property>
<property>
  <name>hive.server2.keystore.path</name>
  <value>/etc/tls/keystore.jks</value>
</property>

Refer to the Hive SSL/TLS configuration documentation for full details.

Cleaning up

To avoid incurring future charges, clean up all provisioned resources during this setup by executing the following cleanup script.

cd ${REPO_DIR}/
./cleanup.sh

Conclusion

In this post, we demonstrated how to implement Kerberos authentication for Amazon EMR on EKS to securely connect to a Kerberos-enabled HMS. This solution addresses a common challenge faced by organizations with existing Kerberos-enabled HMS deployments who want to adopt Amazon EMR on EKS while maintaining their Kerberos-enabled security posture.

This pattern applies whether you’re migrating from on-premises Hadoop, running hybrid Amazon EMR on EC2 or Amazon EMR on EKS environments, or building a new cloud-native platform. Any scenario where Spark jobs on Kerberos must authenticate with a shared, Kerberos-enabled HMS.

You can use this post as a starting point to implement this pattern and extend it further to suit your organization’s data platform needs.


About the authors

Headshot of Krishna Kumar Venkateswaran

Krishna Kumar Venkateswaran is a Cloud Infrastructure Architect at Amazon Web Services (AWS), passionate about building secure applications and data platforms. He has extensive experience in Kubernetes, DevOps, and enterprise architecture, helping customers containerize applications, streamline deployments, and optimize cloud-native environments.

Headshot of Sunil Chakrapani Sundararaman

Sunil Chakrapani Sundararaman is a DevOps Architect at Amazon Web Services (AWS), where he helps enterprise customers architect and implement Data and Machine Learning platforms in the AWS Cloud. He brings extensive experience in Data Platform engineering, MLOps, DevOps, and Kubernetes implementations. Sunil specializes in guiding organizations through their cloud transformation journey, focusing on building scalable and efficient solutions that drive business value.

Headshot of Avinash Desireddy

Avinash Desireddy is a Specialist Solutions Architect (Containers) at Amazon Web Services (AWS), passionate about building secure applications and data platforms. He has extensive experience in Kubernetes, DevOps, and enterprise architecture, helping customers and partners containerize applications, streamline deployments, and optimize cloud-native environments.

Headshot of Suvojit Dasgupta

Suvojit Dasgupta is an Engineering Leader at Amazon Web Services (AWS). He leads engineering teams, guiding them in designing and implementing scalable, high-performance data platforms for AWS customers. With expertise spanning distributed systems, real-time and batch data architectures, and cloud-native infrastructure, he drives technical strategy and engineering excellence across teams. He is passionate about raising the bar on engineering practices, and solving large-scale problems at the intersection of data and business impact.

Building Memory-Intensive Apps with AWS Lambda Managed Instances

Post Syndicated from Guy Haddad original https://aws.amazon.com/blogs/compute/building-memory-intensive-apps-with-aws-lambda-managed-instances/

Building memory-intensive applications with AWS Lambda just got easier. AWS Lambda Managed Instances gives you up to 32 GB of memory—3x more than standard AWS Lambda—while maintaining the serverless experience you know. Modern applications increasingly require substantial memory resources to process large datasets, perform complex analytics, and deliver real-time insights for use cases such as in-memory analytics, Machine Learning (ML) model inference, and real-time semantic search. AWS Lambda Managed Instances gives you a familiar serverless programming model and experience combined with the flexibility of being able to choose the underlying Amazon EC2 instance types and providing developers with access to large memory configurations.

In this post, you will see how AWS Lambda Managed Instances enables memory-intensive workloads that were previously challenging to run in serverless environments, using an AI-powered customer analytics application as a practical example. You’ll see cost savings of up to 33% compared to standard Lambda for predictable workloads, while eliminating the operational overhead of managing EC2 instances.

Understanding AWS Lambda Managed Instances

AWS Lambda Managed Instances runs your AWS Lambda functions on the Amazon EC2 instance types of your choice in your account, including Graviton4 and memory-optimized instance types. AWS handles underlying infrastructure lifecycle including provisioning, scaling, patching, and routing, while you benefit from Amazon EC2 pricing advantages like Savings Plans and Reserved Instances.

Key benefits include:

  • Flexible instance selection: Choose from compute-optimized (C), general-purpose (M), and memory-optimized (R) instance families
  • Configurable memory-CPU ratios: Optimize resource allocation for your workload
  • Multi-concurrent invocations: One execution environment handles multiple invocations simultaneously, improving utilization for I/O-heavy applications
  • Dynamic scaling: Instances scale based on CPU utilization without cold starts

AWS Lambda Managed Instances is best suited for high-volume, predictable workloads that benefit from sustained compute capacity and larger memory configurations.

Memory-Intensive Workloads Work Best with AWS Lambda Managed Instances

This blog focuses on one of AWS Lambda Managed Instances’ most powerful capabilities: running memory-intensive workloads that require more than the standard AWS Lambda’s 10 GB memory and 250MB ZIP limits. Here are the use cases where AWS Lambda Managed Instances helps:

  • In-Memory Analytics — Load gigabytes of structured data into memory at initialization and serve sub-millisecond analytical queries across thousands of invocations
  • ML Model Inference — Keep large model weights resident in memory across invocations for consistent, low-latency inference without a dedicated endpoint.
  • Real-Time Semantic Search — Build vector similarity search over large embedding indexes held entirely in memory, enabling natural language queries over millions of records without an external vector database.
  • Graph Processing — Hold large graph structures in memory for traversal algorithms that require the full graph to be accessible at once.
  • Scientific & Numerical Computing — Run simulations, Monte Carlo methods, and large matrix operations that require substantial working memory and benefit from memory-optimized Amazon EC2 instance families.
  • Large-Scale Report Generation — Aggregate and transform multi-gigabyte datasets in memory to generate complex reports or dashboards on demand, without staging data through intermediate storage.

Use Case: AI-Powered Customer Analytics with AWS Lambda Managed Instances

To demonstrate the power of AWS Lambda Managed Instances for memory-intensive applications, we built an AI-Powered Customer Analytics application that combines in-memory data processing with ML-based semantic search. The application loads in memory 1 million customer behavioral records (sessions, purchases, browsing patterns) from a Parquet file in S3 into a Pandas DataFrame and an embeddings cache consuming 200MB, then responds for analytics queries:

  1. Customer Analysis — Deep-dive into individual customer behavior: engagement scores, conversion rates, purchase patterns, and AI-generated customer segments
  2. Semantic Search — Natural language queries powered by FastEmbed (sentence-transformers/all-MiniLM-L6-v2) that find similar customers using vector similarity
  3. Cohort Analysis — Real-time segmentation by device, country, age group with aggregated metrics

Architecture Overview

Our AI-powered customer analytics application demonstrates this in practice: 1 million records in memory (200MB), a compact sentence transformer model for semantic search, sub-second query performance, and zero infrastructure to manage. The solution uses a simple, serverless architecture:

  • Customer transaction data (Parquet format) is stored in Amazon S3
  • Amazon Cognito User Pool authenticates users and issues JWT tokens for API access
  • Amazon API Gateway routes requests with Cognito authorizer validation, rate limiting (5 requests/second, burst 10), X-Ray tracing, and access logging
  • AWS Lambda function with AWS Lambda Managed Instances loads the entire dataset (200MB) and all-MiniLM-L6-v2 model (900MB) into memory during initialization while also performing a threaded embeddings cache generation. This step can consume about 14GB of the allocated memory, exceeding standard AWS Lambda’s 10 GB limit
  • Analytics queries execute against the in-memory data using the model
  • Results are returned in milliseconds for interactive analysis

Architecture diagram

Deploy the Application

The below steps walk you through deploying the application to AWS using the AWS Serverless Application Model (SAM). The deployment process packages your Lambda function code, uploads artifacts to Amazon S3, and provisions all required AWS resources including Lambda functions, IAM roles, and any configured VPC networking via AWS CloudFormation.

Prerequisites

Make sure you have the following tools installed locally:

  • AWS CLI configured with credentials
  • SAM CLI installed
  • Python 3.13+ installed locally
  • Docker or Finch (required for container builds)
  • AWS account with appropriate permissions
  • A VPC with at least 2 subnets (across different Availability Zones) and a security group — required for the Lambda Managed Instances capacity provider
  • Supported regions: Check AWS Capabilities by Region for supported regions

Getting Started

The complete source code for this application is available in our GitHub repository. To deploy it yourself follow the below steps and refer to the full deployment instructions hosted on GitHub.

1. Clone the repository

git clone https://github.com/aws-samples/sample-lambda-managed-instances-analytics.git

2. Navigate to the project folder

cd sample-lambda-managed-instances-analytics

chmod +x setup-data.sh deploy-lambda.sh

3. Generate sample data and upload to S3

./setup-data.sh

This script will create an S3 bucket (if needed), generate 1M rows of sample data, and upload the data to S3.

4. Build and deploy the Lambda function

./deploy-lambda.sh

This script will build the container image with FastEmbed, push it to ECR, and deploy the Lambda function along with Capacity Provider, API Gateway, and Cognito User Pool. After deployment, it automatically generates the UI authentication configuration and prompts you to create a test user.

SAM template

Capacity provider configuration

Run the Application

1. Start the UI

The application includes a simple HTML-based UI through which you can test the AWS Lambda function using Amazon API Gateway:

cd ui && python3 -m http.server 8000

2. Open your browser at http://localhost:8000 and click ‘Sign In’ to authenticate via Cognito using the username/password that you created during deployment
Starting the UI

3. Enter your API endpoint URL. Test connection and click system Info.

Testing the connection

Test the Application

a. Customer Analysis — Enter one or more User IDs to get more information on the customer behavior: engagement scores, conversion rates, purchase patterns, and AI-generated customer segments

Running customer analysis

b. Semantic Search – Enter natural language queries like “list high value customers from USA” in the Semantic Search and verify the results. Note that the response is very fast as the analytics data and FastEmbed models are loaded into memory during init stage

Running semantic search

c. Cohort Analysis — Enter the query data to get Real-time segmentation by device, country, age group with aggregated metrics

Running cohort analysis

Observability

AWS Lambda Managed Instances automatically publishes metrics to Amazon CloudWatch, giving you visibility into function performance and capacity utilization. Monitor InitDuration to track dataset and model load time at startup, MaxMemoryUsed to confirm your data fits within configured memory, and ProvisionedConcurrencySpilloverInvocations to detect when AWS Lambda Managed Instances capacity is exhausted.

Enable AWS Lambda Insights for enhanced per-invocation metrics including CPU time and memory utilization over time. Use Amazon CloudWatch Log Insights to query INIT_START, INIT_END, and REPORT log entries for initialization and memory details per invocation.

AWS Lambda Insights

What Makes This Better with AWS Lambda Managed Instances

Without AWS Lambda Managed Instances, building this same application would require one of these alternatives:

  • Option A: EC2 with auto-scaling — Full control, full responsibility: patching, scaling policies, load balancing, and deployment pipelines — all on you.
  • Option B: Redesign for standard Lambda — Swap in-memory data for an external database and replace the ML model with Amazon SageMaker endpoint. More latency, more cost, more complexity.

With AWS Lambda Managed Instances, you write a single AWS Lambda function, define a Capacity Provider, and deploy with SAM. AWS Lambda handles the Amazon EC2 instances, scaling, and lifecycle, giving you the memory you need with the operational simplicity you want. The in-memory approach eliminates network latency and disk I/O, delivering consistent sub-200ms response times for complex analytics.

Cost Considerations

AWS Lambda Managed Instances uses Amazon EC2-based pricing with a management fee. For predictable workloads, you can leverage Amazon EC2 Savings Plans or Reserved Instances to reduce costs significantly.

Example cost comparison (us-east-1, 32 GB memory, 1M invocations/month):

  • AWS Lambda (standard): ~$267/month (on-demand pricing)
  • AWS Lambda Managed Instances: ~$180/month (with 1-year Compute Savings Plan)
  • Savings: 33% reduction

The cost benefits increase with higher memory configurations and sustained workloads that can take advantage of Amazon EC2 pricing discounts.

Best Practices

Based on experience building this solution, here are key recommendations:

  • Memory sizing: Start with your dataset size plus 50% overhead for processing. Monitor Amazon CloudWatch metrics to optimize.
  • Initialization strategy: Load large datasets during the init phase to amortize the cost across multiple invocations.
  • Concurrency configuration: Set PerExecutionEnvironmentMaxConcurrency based on your workload’s I/O characteristics. Higher values work well for I/O-bound analytics.
  • Data format: Use columnar formats like Parquet for efficient memory usage and fast loading.
  • Monitoring: Track initialization duration, memory utilization, and invocation latency in Amazon CloudWatch to identify optimization opportunities.

Cleanup

When you’re done exploring the solution, it’s good practice to remove all provisioned resources to avoid ongoing charges. For the full cleanup commands and exact steps, refer to the project’s README.md in GitHub repository.

Conclusion

AWS Lambda Managed Instances opens up a new class of serverless applications that support larger AWS Lambda layer packages and more memory. Memory-intensive workloads — in-memory analytics, ML inference, graph processing, scientific computing — can now run with the simplicity of AWS Lambda and the resources of Amazon EC2. The customer analytics example demonstrates how in-memory processing with AWS Lambda Managed Instances delivers performance improvements over traditional database queries while maintaining serverless benefits like automatic scaling and pay-per-use pricing.

Ready to get started? Explore the AWS Lambda Managed Instances documentation and try building your own memory-intensive serverless application. You can find the complete code for this example on GitHub.

Build a multi-tenant configuration system with tagged storage patterns

Post Syndicated from Koshal Agrawal original https://aws.amazon.com/blogs/architecture/build-a-multi-tenant-configuration-system-with-tagged-storage-patterns/

In modern microservices architectures, configuration management remains one of the most challenging operational concerns. Two gaps emerge as organizations scale: handling tenant metadata that changes faster than cache TTL allows, and scaling the metadata service itself without creating a performance bottleneck.

Traditional caching strategies force an uncomfortable trade-off: either accept stale tenant context (risking incorrect data isolation or feature flags), or implement aggressive cache invalidation that sacrifices performance and increases load on your metadata service. When tenant counts grow into the hundreds or thousands, this metadata service itself becomes a scaling challenge, particularly when different configuration types have vastly different access patterns.

The challenge intensifies when you need to support different storage backends for different configuration types. Some require high-frequency access patterns suited for Amazon DynamoDB, while others benefit from the hierarchical organization and built-in versioning of AWS Systems Manager Parameter Store. Traditional solutions often force engineering teams into a corner: either build multiple configuration services (increasing operational overhead), or compromise on performance by using a single storage backend that isn’t optimized for every use case.

In this post, we demonstrate how you can build a scalable, multi-tenant configuration service using the tagged storage pattern, an architectural approach that uses key prefixes (like tenant_config_ or param_config_) to automatically route configuration requests to the most appropriate AWS storage service. This pattern maintains strict tenant isolation and supports real-time, zero-downtime configuration updates through event-driven architecture, alleviating the cache staleness problem.

What you’ll learn:

  • Implementing a multi-tenant data model with DynamoDB and Parameter Store
  • Using the Strategy pattern for flexible storage backend switching
  • Building tenant isolation through JSON Web Token (JWT) claims
  • Creating an event-driven auto-refresh mechanism with Amazon EventBridge and AWS Lambda
  • Implementing zero-downtime configuration updates with gRPC (a high-performance communication protocol) streaming
  • Addressing the cache TTL problem for rapidly-changing tenant metadata

By the end of this post, you’ll understand how to architect a configuration service that handles complex multi-tenant requirements while optimizing for both performance and operational simplicity.

Solution overview

The architecture uses four AWS services orchestrated through a NestJS-based gRPC service to create a reliable, event-driven configuration management system. Let’s first understand the overall architecture before diving into each component’s implementation details.

Architecture components

The following diagram shows the end-to-end architecture of the Multi-Tenant Configuration Service deployed on AWS, from how client requests enter the system to how configuration data is retrieved from the right storage backend.

WS microservices architecture diagram showing ECS Fargate services, API Gateway, Cognito auth, DynamoDB, and CloudWatch monitoring

Figure 1: Multi-Tenant Configuration Service Architecture

Client applications authenticate via Amazon Cognito and pass through AWS WAF before reaching Amazon API Gateway. Traffic is then routed through a VPC Link to an Application Load Balancer, which distributes requests across two core microservices running on Amazon Elastic Container Service (Amazon ECS) on AWS Fargate within private subnets :

  • Order Service— handles incoming REST requests and delegates configuration lookups to the Config Service via gRPC
  • Config Service— exposes a gRPC API and uses a Config Strategy Factory to dynamically select the appropriate storage backend (DynamoDB or Parameter Store) based on the request

Service discovery is managed by AWS Cloud Map, while Amazon CloudWatch centralizes logs and metrics across services.

The system is organized into four interconnected layers, each addressing a specific aspect of the configuration management challenge:

1. Storage layer – multi-backend strategy

The storage layer strategically uses two complementary AWS services, each optimized for different configuration access patterns and requirements.

  • Amazon DynamoDB: Stores tenant-specific configurations. These are settings unique to each customer, such as payment gateway preferences or feature flags. With single-digit millisecond latency, DynamoDB handles high-frequency reads efficiently. The schema uses composite keys (TENANT#{tenantId} as partition key, CONFIG#{configType} as sort key) for efficient tenant-scoped queries and built-in multi-tenant isolation at the data model level.
  • AWS Systems Manager Parameter Store: manages shared parameters. These are configuration values used across multiple services or tenants, such as API endpoints, database connection strings, and region-specific settings. Unlike tenant-specific configs that change frequently, these parameters are relatively static but benefit from hierarchical organization. The path structure (/config-service/{tenantId}/{service}/{parameter}) enables bulk retrieval operations, reducing the number of API calls needed during service initialization from dozens to a single request.

2. Service layer – gRPC with strategy pattern

A NestJS-based microservice implements the configuration retrieval logic using gRPC for high-performance, type-safe communication. This choice significantly reduces network bandwidth and improves response times for service-to-service communication where compatibility with web browsers isn’t a requirement.

At the core is a Strategy Pattern implementation that determines the optimal storage backend based on configuration key prefixes. This pattern simplifies the addition of new storage backends (like Amazon Simple Storage Service (Amazon S3) for large configuration files) without modifying the core service logic.

3. Authentication layer – Amazon Cognito

User authentication flows through Amazon Cognito with custom attributes:

  • custom:tenantId (immutable) – Tenant identifier embedded in JWT
  • custom:role (mutable) – User role for authorization

Critical security design: The service never accepts tenantId from request parameters. Instead, it extracts the tenant context from validated JWT tokens, making sure requests cannot access other tenants’ data even if they attempt to manipulate request payloads.

4. Event-driven refresh layer

Traditional configuration updates present a dilemma: how do you keep services synchronized without compromising performance or causing downtime?

Polling approaches continuously check for changes, generating unnecessary API calls that cost money even when nothing changes. They also introduce delays. Services don’t see updates until the next poll cycle, which could be seconds or minutes later.

Service restart approaches cause downtime, drop active connections, and disrupt user sessions. For SaaS applications serving customers 24/7, restart-based updates are unacceptable.

The event-driven refresh layer addresses both problems by implementing a reactive architecture where Amazon EventBridge monitors Parameter Store for changes and triggers AWS Lambda to update the service’s local cache. This achieves configuration updates within seconds while users experience no interruption.

Technical implementation

The following sections detail the implementation, starting with the data model, which serves as the backbone for tenant isolation and efficient querying.

A. Multi-tenant data model

The foundation of tenant isolation begins with the data model. Using DynamoDB’s composite key structure, we achieve both tenant isolation and efficient querying without requiring separate tables per tenant.

DynamoDB schema design:

The following example shows a tenant-specific configuration stored in DynamoDB, illustrating how composite keys enable both isolation and efficient access:

{
  "pk": "TENANT#acme-corp",
  "sk": "CONFIG#payment-gateway",
  "config": {
    "providers": [
      {
        "name": "Stripe",
        "apiEndpoint": "https://api.stripe.com",
        "retryPolicy": "exponential"
      }
    ]
  },
  "isActive": true,
  "version": 2,
  "createdAt": "2024-01-15T10:30:00Z",
  "updatedAt": "2024-02-20T14:45:00Z"
}

Key schema decisions:

  1. Partition key pattern: TENANT#{tenantId} makes sure tenant data is co-located, enabling efficient tenant-scoped queries while maintaining logical separation.
  2. Sort key pattern: CONFIG#{configType} allows querying specific configuration types within a tenant’s data. The CONFIG# prefix enables future expansion with other entity types (for example, METADATA#, AUDIT#).
  3. Soft deletion: The isActive boolean flag supports soft deletion, maintaining audit trails while excluding inactive configurations from queries.
  4. Versioning: The version field tracks configuration changes, supporting rollback capabilities and change history.

Parameter store organization:

Parameters follow a hierarchical structure that mirrors the multi-tenant model. This example demonstrates the path structure:

/config-service/
├── acme-corp/
│   ├── api/
│   │   ├── api-key
│   │   └── endpoint
│   └── database/
│       └── connection-string
└── globex-inc/
    ├── api/
    │   ├── api-key
    │   └── endpoint
    └── database/
        └── connection-string

This structure provides several benefits:

  • Bulk retrieval using path prefix (GetParametersByPath API)
  • Clear ownership and access control through AWS Identity and Access Management (AWS IAM) policies
  • Environment separation (dev/staging/prod) at the path level
  • Automatic parameter versioning and change tracking

Advanced: Multi-dimensional tenant context
For organizations with multiple services requiring different configuration scopes, consider introducing a second dimension in the partition key:

PK = "TENANT#acme-corp|SERVICE#order-service"
SK = "CONFIG#payment-gateway"

This multi-dimensional approach enables service-level isolation where the Order service sees only billing API configurations while the Reporting service doesn’t have access to payment gateway settings. It also provides efficient service-scoped queries, retrieve configurations for a specific service with PK = TENANT#acme-corp|SERVICE#order-service and SK begins with CONFIG#. The second dimension can represent business units, geographic regions, or a logical boundary that aligns with access control requirements, making this pattern particularly valuable when fine-grained access control beyond tenant-level isolation is needed. For detailed guidance on multi-tenant DynamoDB modelling patterns, see amazon-dynamodb-data-modeling-for-multi-tenancy-part-2.

B. Strategy pattern for storage flexibility

The system decides which storage backend to use for each configuration request. The Strategy Pattern is a design approach that allows a program to choose different behaviors at runtime based on context. Think of it like a traffic controller that examines each request and directs it to the appropriate service.

Why use the strategy pattern?

Without the Strategy Pattern, handling multiple storage backends would require complex conditional logic throughout the code base. Different tenant metadata has vastly different access patterns. Routing to optimized backends alleviates both DynamoDB cost explosions (for rarely-changing configs) and Parameter Store throttling (for high-frequency reads), addressing the scaling gap. A naive implementation might look something like this and it’s worth pausing to understand why this approach breaks down.

// Without Strategy Pattern - complex and hard to maintain
async getConfig(key: string, tenantId: string) {
  if (key.startsWith('tenant_config_')) {
    // DynamoDB logic here
    const pk = `TENANT#${tenantId}`;
    const sk = `CONFIG#${key.slice(14)}`;
    return await this.dynamoDB.query({...});
  } else if (key.startsWith('param_config_')) {
    // Parameter Store logic here
    const path = `/config-service/${tenantId}/${key.slice(13)}`;
    return await this.ssm.getParameter({...});
  }
  // More conditions as backends are added...
}

Every time you add a new storage backend, say, AWS Secrets Manager or Amazon S3, you’re forced to reach back into this function and bolt on another else if. The storage logic becomes tightly coupled to your service layer, making it harder to test each backend in isolation and nearly impossible to swap one out without risking regressions elsewhere.

Implementation strategy

The Strategy Pattern encapsulates storage-specific logic into separate, interchangeable strategy classes. This code demonstrates how the factory examines keys and selects strategies:

@Injectable()
export class ConfigStrategyFactory {
  private keyStrategyMap = new Map<string, ConfigStrategy>([
    ['tenant_config_', this.dynamoDBConfigStrategy],
    ['param_config_', this.ssmConfigStrategy],
  ]);
  getStrategy(key: string): ConfigStrategy {
    for (const [prefix, strategy] of this.keyStrategyMap.entries()) {
      if (key.startsWith(prefix)) {
        return strategy;
      }
    }
    throw new ValidationException(`Invalid key format: ${key}`);
  }
}

Key prefix mapping:

  • tenant_config_* → Routes to Amazon DynamoDB for tenant-specific, high-frequency access patterns
  • param_config_* → Routes to AWS Systems Manager Parameter Store for shared, hierarchical parameters

With this approach, adding a new storage backend requires only:

  • Creating a new strategy class implementing the ConfigStrategy interface
  • Adding one line to the keyStrategyMap with the new prefix and strategy
  • No changes to existing strategies or calling code

This design helps protect technology investments. As requirements evolve and new AWS services become relevant, the system adapts without major rewrites.

Multi-layer caching strategy

Different configurations benefit from different caching approaches. The pattern implements different caching strategies optimized for each configuration type’s access patterns and business requirements:

  • High-frequency tenant configurations (accessed thousands of times per minute) use application-level caching with short Time-To-Live (TTL) values. This significantly reduces database queries while maintaining reasonably fresh data.
  • Shared parameters (accessed frequently but change rarely) use in-memory caching with event-driven invalidation. The cache only refreshes when EventBridge detects an actual change, alleviating unnecessary API calls.

Cache Security Considerations

The implementation uses a shared in-memory Map with tenant-prefixed keys (tenantId:serviceName:configKey). Cached values are configuration metadata (API endpoints, feature flags, thresholds), not sensitive data like credentials or PII. Sensitive values remain in Parameter Store with SecureString encryption and are retrieved on-demand, not cached. Even in edge cases, downstream access controls (JWT validation, DynamoDB composite keys) act as the final enforcement boundary.

For teams handling more sensitive configuration payloads, consider Amazon ElastiCache (Redis OSS) or Valkey with key-prefix isolation and encryption at rest/in transit, though this adds 1-3ms network latency versus sub-millisecond in-memory access.

C. Authentication and tenant isolation

Tenant isolation is enforced at multiple layers, starting with JWT-based authentication and custom authorization guards.

Cognito JWT validation flow:

  1. Client authenticates with Cognito and receives JWT token
  2. Request includes JWT in Authorization: Bearer {token} header
  3. CognitoJwtGuard validates token signature against Cognito JSON Web Key Sets (JWKS) endpoint
  4. Guard extracts custom:tenantId claim and attaches to request context
  5. TenantAccessGuard verifies user has access to requested tenant
  6. Service layer uses validated tenantId for data operations

This implementation demonstrates the secure approach to tenant context extraction:

async retrieveConfig(req: RetrieveConfigRequest): Promise<RetrieveConfigResponse> {
  // tenantId is extracted from validated JWT token, never from request parameters
  const tenantId = (req as any).tenantId;
  if (!tenantId) {
    throw new UnauthorizedException('Tenant ID not found in authentication context');
  }
  const strategy = this.strategyFactory.getStrategy(req.key);
  const data = await strategy.getConfig(req.serviceName, req.key, tenantId);
  return { data };
}

Why this approach helps prevent unauthorized access:

Consider what happens if an unauthorized user tries to access another tenant’s configuration:

  1. User authenticates as Tenant A and receives JWT with custom:tenantId: "tenant-a"
  2. User attempts to manipulate request to access Tenant B’s data
  3. The service extracts tenantId from the JWT (still “tenant-a”), ignoring request parameters
  4. Query uses the JWT’s tenant ID, so user only sees Tenant A’s data

Advanced: Infrastructure-level credential isolation

The current design enforces tenant isolation at the application layer through JWT extraction and DynamoDB composite keys. The ECS task uses a shared IAM execution role, meaning tenant requests operate under the same AWS credentials. While this approach is sufficient for most multi-tenant applications, teams with stricter compliance requirements (HIPAA, PCI-DSS, FedRAMP) may need infrastructure-level isolation.

For enhanced isolation, consider implementing a Token Vending Machine (TVM) pattern with AWS Security Token Service (STS) to issue temporary, tenant-scoped IAM credentials. This provides infrastructure-level isolation with per-tenant AWS CloudTrail audit trails and principle of least privilege enforcement. However, TVM adds operational complexity (credential caching, STS API costs, token refresh logic) and latency (50-100ms per operation).

Consider this as a next step when compliance auditors require infrastructure-level separation rather than a baseline requirement.

This design helps prevent cross-tenant access attempts at the infrastructure level, addressing a common security issue.

D. Zero-downtime auto-refresh mechanism

Configuration updates in production systems present a classic operations challenge. This event-driven approach addresses the cache TTL trade-off entirely, configurations update in real-time without polling or staleness windows.

EventBridge integration flow:

1. Parameter Store Change
         ↓
2. EventBridge Rule (matches /config-service/* changes)
         ↓
3. Lambda Function (extracts tenantId from path)
         ↓
4. Service Discovery (AWS Cloud Map queries for healthy instances)
         ↓
5. gRPC Refresh Call (direct service-to-service invocation)
         ↓
6. In-Memory Cache Update (zero-downtime)
         ↓
7. Updated Configuration Active (no connection drops)

Key benefits:

  1. Zero downtime: No service restarts required. Connections remain active
  2. Reactive updates: Only triggers when changes occur (no wasteful polling)
  3. Cost efficient: Minimizes SSM API calls through caching and event-driven refresh
  4. Audit trail: EventBridge provides complete change history and monitoring

When to use this pattern?

The tagged storage pattern isn’t universally applicable. Like most architectural approaches, it has ideal use cases where the benefits significantly outweigh the implementation complexity. Consider this pattern when your application matches these characteristics:

  • Multi-tenant SaaS requiring strict tenant isolation and regulatory compliance benefit significantly. The pattern’s infrastructure-level isolation through JWT claims and data model design provides security commitments that application-level isolation cannot match.
  • Microservices architectures with complex configuration requirements across dozens of services find value in the centralized management and flexible storage routing.
  • Organizations managing configurations across multiple storage backends and environments (dev, staging, production, DR) appreciate the hierarchical organization and path-based access control that Parameter Store provides, combined with DynamoDB’s performance for high-frequency access.
  • High-throughput applications (1000+ requests/second) needing sub-millisecond response times use DynamoDB Accelerator (DAX) for in-memory caching. While DynamoDB offers excellent single-digit millisecond latency, DAX delivers microsecond read latency, typically 5-10x faster for cached data. This makes a substantial difference at scale.
  • Teams prioritizing operational simplicity value the event-driven refresh mechanism that avoids manual deployment coordination.

Getting started

Ready to implement the Tagged Storage Pattern in your organization?

Start with a pilot project focusing on a single microservice and gradually expand the pattern across your architecture. The modular design means that you can realize benefits incrementally while building confidence in the approach.

Implementation steps:

  1. Design your data model: Define DynamoDB schema and Parameter Store hierarchy
  2. Set up Amazon Cognito: Configure user pool with custom tenant attributes
  3. Build the service layer: Implement Strategy Pattern for storage routing
  4. Add event-driven refresh: Configure EventBridge rules and Lambda function
  5. Test tenant isolation: Verify JWT validation and cross-tenant access deterrence
  6. Deploy and monitor: Establish CloudWatch dashboards and operational procedures

You can find the complete code for this solution, including AWS CloudFormation templates, deployment and testing scripts, in the GitHub – Configuration Management Service.

To avoid incurring ongoing charges, delete the resources you created during this walkthrough. For detailed cleanup instructions including step-by-step commands and verification steps, see the Infrastructure Cleanup Guide.

Conclusion

Building a multi-tenant configuration service requires careful consideration of storage patterns, security boundaries, and operational requirements. The tagged storage pattern demonstrated in this post provides a flexible, scalable foundation that addresses these challenges through:

  1. Intelligent storage routing: The Strategy Pattern provides optimal backend selection per configuration type, allowing DynamoDB for tenant-specific settings and SSM Parameter Store for shared parameters.
  2. Zero-downtime updates: Event-driven architecture through EventBridge and Lambda avoids service restarts and polling overhead so that configurations refresh immediately upon changes.
  3. Strong tenant isolation: JWT-based authentication with custom claims makes sure tenant boundaries are enforced at the infrastructure level, not application logic, helping prevent cross-tenant access attempts.
  4. Operational simplicity: In-memory caching, combined with event-driven refresh, can reduce API costs while maintaining microsecond response times.
  5. Cost efficiency: Pay-per-request billing, aggressive caching, and Spot instances help keep operational costs minimal even at scale.

Additional resources


About the authors

A framework for securely collecting forensic artifacts into S3 buckets

Post Syndicated from Jason Garman original https://aws.amazon.com/blogs/security/a-framework-for-securely-collecting-forensic-artifacts-into-s3-buckets/

When customers experience a security incident, they need to acquire forensic artifacts to identify root cause, extract indicators of compromise (IoCs), and validate remediation efforts. NIST 800-86, Guide to Integrating Forensic Techniques into Incident Response, defines digital forensics as a process comprised of four basic phases: collection, examination, analysis, and reporting. This blog post focuses on the first phase—collection—and provides best practices for implementing least privilege during the forensic evidence collection processes that collect evidence and store the artifacts in Amazon Simple Storage Service (Amazon S3) buckets. The architecture presented in this post can be used to collect forensic evidence from both Amazon Web Services (AWS) and non-AWS compute resources.

It’s important to consider the security of the forensic artifact collection process because it involves communicating with potentially compromised resources. The collection methodology itself should be designed to avoid adding additional risks to infrastructure or other forensic investigation processes. At the same time, the collection of forensic artifacts requires the use of specialized tools that are difficult to change or adapt to new security requirements.

This post outlines factors that you should consider when creating an evidence collection capability and introduces an architecture that implements the best practices for least privilege and integrating with (instead of changing or adapting) existing forensic tools that support uploading artifacts to S3 buckets by using AWS security credentials.

Solution architecture

The architecture presented in this post demonstrates the following AWS best practices:

  1. Least privilege – Use AWS Identity and Access Management (IAM) policies to provide least privilege access to upload forensic artifacts to an S3 location dedicated to a specific forensic collection task. The locked down credentials cannot be used to view or modify any other forensic collections.
  2. Time-limited credentials – Use AWS Security Token Service (AWS STS) to provide time limited credentials, reducing the potential for an unauthorized user to abuse credentials while they’re visible on the target machine during the artifact collection process.
  3. Compatibility with third-party tools – Forensic tools are specialized and changing a forensic collection process to adapt to different collection methods might not be possible. To avoid the risk of needing to change tools, maximize compatibility with any third-party tools that support uploading to S3 buckets. The method introduced in this post to generate time-limited, scoped down credentials can be used with most third-party forensic tools that support uploading to S3 buckets.
  4. Credential vending – Use time-limited tokens, which can be vended on demand through an automated process, eliminating the need for forensic investigators to use the AWS Management Console, understand least privilege, or have any access to the AWS control plane. Forensic investigators can focus on the process of collecting and analyzing evidence.
  5. Process automation – Deploy the process as infrastructure as code (IaC) and automate it through AWS services, reducing the burden on security teams to manually perform runbook steps during an active security incident.

This post starts with an overview of the digital forensic process, provides best practices for using Amazon S3 to store forensic artifacts, details how you can create time-limited, least privilege tokens to provide secure access to upload forensic artifacts to S3 buckets, and introduces a sample architecture that automates the end-to-end process.

The digital forensic process

Organizations need to have practices and resources in place to support a digital forensic investigation environment before an incident occurs. AWS has published several resources, including Forensic investigation environment strategies in the AWS Cloud and AWS prescriptive guidance: Security Reference Architecture, Cyber forensics, to provide best practices for organizing your AWS accounts using AWS Organizations to support forensic clean-room environments. Creating segregated AWS accounts and resources for your security teams is critical to provide your incident responders a location to store and analyze any digital forensic evidence collected during an investigation.

After you’ve established a landing zone for performing digital forensics, you’re ready to collect and process digital forensic evidence. AWS supports the collection of digital forensics through extensive logging of control plane events in AWS CloudTrail, and metrics and application logs that can be stored in Amazon CloudWatch. In addition, AWS core compute services, such as Amazon Elastic Compute Cloud (Amazon EC2), support forensics operations through snapshots of the underlying Amazon Elastic Block Storage (Amazon EBS) volume. An example architecture to demonstrate how to automate the collection of EBS volume snapshots for forensic investigations can be found in How to automate forensic disk collection in AWS.

You might want to use the same AWS infrastructure to collect, examine, analyze, and report on forensic incidents that occur on other resources, such as corporate laptops. You can use existing forensic tooling to perform live response, collecting specific artifacts such as Windows NT File System (NTFS) Master File Table (MFT), logs from Linux machines, volatile memory images, or other artifacts that are specified as part of your organization’s incident response plan. These tools can be provided by third parties or built in-house, and many support uploading to S3 buckets using AWS security credentials.

Using Amazon S3 for forensic artifact collection

Amazon S3 provides the foundational requirements for collecting and storing forensic artifacts. Digital forensics requires highly available, durable, and secure storage of artifacts collected from potentially compromised systems. Amazon S3 is designed for 11 nines of durability and can be configured to provide protection against modification, deletion, and unauthorized access to sensitive forensic artifacts. You can also use S3 to store forensic artifacts of almost any size—from one byte to 5 TB—in an S3 object.

S3 buckets used to store forensic artifacts require custom configuration to provide additional security. You should configure the S3 bucket that you use to store forensic artifacts to enable the following security and governance features:

  1. Encryption in transit. You can require the use of encryption in transit and specify acceptable TLS versions using the aws:SecureTransport and s3:TlsVersion condition keys on the S3 bucket policy.
  2. Encryption at rest using a customer managed key. You can automatically encrypt all objects uploaded to the bucket using a specified customer managed key by specifying a default server-side encryption key in the bucket’s configuration. For this post, we encourage you to use a customer managed key rather than relying upon an AWS managed key, so you can control the associated key policy.
    1. Encryption at rest provides an additional layer of protection, because only entities that have both the permission to read from the bucket and permission to use the AWS Key Management Service (AWS KMS) key for decryption can download the forensic artifact from the S3 bucket.
    2. You need to adjust the example KMS policies in this post if the evidence collection S3 bucket uses the S3 Bucket Key feature.
  3. Audit logs of all S3 data event activity. You can turn on CloudTrail data events for any S3 buckets that contain forensic artifacts to provide a comprehensive audit trail of S3 object-level API activity. This helps provide a chain of custody of any artifacts stored in your forensic buckets.
  4. Fine-grained access control using IAM permissions. You can define the set of entities (both human and machine) that have access to the artifacts in the S3 bucket. This post includes how to create time-limited, least privilege access using IAM permissions for uploading files into an S3 bucket. The permissions are fine-grained enough to scope down access to specific object names or object prefixes in an S3 bucket. Additionally, access to read the artifacts can be controlled through IAM permissions and access to the encryption-at-rest KMS key.
  5. Protections against data modification and deletion. S3 provides features, such as S3 object versioning, to provide assurances that data hasn’t been modified or removed after it’s been collected. This is an additional layer of protection beyond the fine-grained access permissions, so even if an authorized entity attempts to overwrite or delete an object in the S3 bucket, the previous version of the object is still available.
  6. There are additional options that you can configure on the S3 bucket to protect your data against modification and deletion, including S3 Object Lock and multi-factor authentication (MFA) delete.

In addition to the preceding configuration, consider how to organize forensic artifacts in the S3 bucket. This post introduces a folder structure using S3 object prefixes to segregate each forensic artifact collection task into its own S3 object namespace. An example S3 namespace structure for an S3 bucket is shown in Figure 1.

Figure 1 – S3 namespace structure for an S3 forensics artifact bucket using object prefixes

Figure 1: S3 namespace structure for an S3 forensics artifact bucket using object prefixes

By separating each forensic collection task by its own prefix, you can use fine-grained IAM permissions to permit object uploads only into the active collection task. For example, scoped down credentials can be generated to only allow uploads into buckets with the CASE-0001 prefix using an IAM permission as shown in the following code example. Temporary security credentials can be generated using these limited permissions and the key is then used by the forensic acquisition tool to upload the artifacts into the S3 bucket.

{
	"Sid": "UploadToCase0001",
	"Effect": "Allow",
	"Action": [
		"s3:PutObject",
		"s3:AbortMultipartUpload"
	],
"	Resource": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"
}

Manually creating temporary IAM credentials for each forensic collection activity can be error-prone and time-consuming. Therefore, this post demonstrates how to use AWS tooling to automate the process of generating time-limited, scoped-down credentials.

Adapt existing forensic tools for AWS best security practices

Existing forensic tools typically use IAM access keys to perform S3 operations. Using a static IAM user secret access key isn’t a best practice. Even if the static key is associated with an IAM user that has been scoped down to only have access to the forensic collection S3 bucket as described previously, that means anyone with access to that key can potentially upload objects into that bucket. Therefore, the best practice is to create a time-limited temporary security credential unique to each collection activity, scoped down to only allow uploading files to a specific prefix in the target S3 bucket.

The examples in this post use the following resource names. Because these names will change based on your deployment, substitute your resource names in place of the names in the example code.

  1. The evidence S3 bucket is named mycompany-forensics-collection
  2. The forensics AWS account number is 112233445566. For the purposes of this example, all resources will live within this account.
  3. The customer managed key used to encrypt the forensic artifacts at rest is ForensicsEvidenceKey
  4. The IAM role that incident responders will assume when signing in to their AWS account is ForensicsUserRole
  5. The IAM role that incident responders will use for generating S3 file upload temporary credentials is ForensicsUploadRole
  6. The example uses the us-east-1 AWS Region

The following steps show you how to configure the IAM policies associated with the customer managed key ForensicsEvidenceKey and the IAM role ForensicsUploadRole.
Before you begin, create the evidence S3 bucket configured as described in Using S3 for artifact collection and a customer managed key to encrypt the forensic artifacts at rest. Configure the evidence S3 bucket to use the KMS key by opening the S3 bucket’s properties tab in the Amazon S3 console and setting the new KMS key as the default encryption key for the bucket.

Next, create an IAM role that incident responders will assume through the AWS STS AssumeRole API to generate the temporary credentials. This role will define the maximum set of permissions allowed to upload artifacts to your evidence S3 bucket. This role, ForensicsUploadRole, created using the following example code, defines the maximum allowable permissions: the ability to upload objects into the evidence S3 bucket and to use the KMS key to encrypt those uploads. The effective permissions available to the forensic tool will be scoped down even further to the specific object prefix when the AWS STS temporary security credential is generated.

Note that the policy allows the forensics upload role Decrypt permission in addition to Encrypt; this is required when uploading files larger than 5 GB using the multi-part S3 file upload feature.

{
	"Version": "2012-10-17",
	"Statement": [
			{
				"Sid": "BasePermissionsForS3Upload",
				"Effect": "Allow",
				"Action": [
					"s3:PutObject",
					"s3:AbortMultipartUpload"
				],
				"Resource": "arn:aws:s3:::mycompany-forensics-collection/*"
		},
		{
			"Sid": "KeyAccessToS3Upload",
			"Effect": "Allow",
			"Action": [
				"kms:GenerateDataKey",
				"kms:Encrypt",
				"kms:Decrypt"
			],
			"Resource": "arn:aws:kms:us-east-1:112233445566:alias/ForensicsEvidenceKey",
			"Condition": {
				"StringLike": {
					"kms:EncryptionContext:aws:s3:arn": "arn:aws:s3:::mycompany-forensics-collection/*"
				}
			}
		}
	]
}

Next, you need to provide an ability to assume this role and generate AWS STS tokens using the role’s permissions. This is accomplished by creating a trust relationship associated with the IAM role you just created. The trust relationship shown in the following code sample describes which AWS principals are allowed to assume the role—in this case, you will allow any user who has federated into the ForensicsUserRole IAM role to be able to generate AWS STS tokens for forensic artifact collection.

{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Sid": "Statement1",
			"Effect": "Allow",
			"Principal": {
				"AWS": "arn:aws:iam::112233445566:role/ForensicsUserRole"
			},
			"Action": "sts:AssumeRole"
		}
	]
}

After the role is established and access to the encryption key is granted, you can use the AWS STS AssumeRole API to create temporary credentials using this role. You can call this API using the AWS Command Line Interface (AWS CLI) or programmatically from a script. To scope down the token’s access to only provide permission to upload to the specific evidence object prefix, you must include a session policy as part of your AssumeRole API request to AWS STS. The following is an example session policy to restrict access to only upload objects into the CASE-0001 prefix.

[
	{
		"Effect": "Allow",
		"Action": [
			"s3:PutObject", 
			"s3:AbortMultipartUpload"
		],
		"Resource": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"
	},
	{
		"Effect": "Allow",
		"Action": [
			"kms:GenerateDataKey", 
			"kms:Encrypt", 
			"kms:Decrypt"
		],
		"Resource": "*",
		"Condition": {
			"StringLike": {
				"kms:EncryptionContext:aws:s3:arn": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"
			}
		}
	}
]

The effective permissions available to the session role will be the intersection of permissions available in the role policy (ForensicsUploadRole), the resource policy (in this case, mandating TLS-encrypted connections to the bucket), and the session policy that’s created on demand for every forensic collection (only allowing access to upload objects into the CASE-0001 prefix, as shown in the preceding example). Pictorially, this looks like the Venn diagram shown in Figure 2.

Figure 2 – Intersection of IAM policies determine the effective permissions for the restricted forensic session role.

Figure 2: Intersection of IAM policies determine the effective permissions for the restricted forensic session role.

Test the temporary credentials

Now that the bucket has been created and the AWS KMS key and roles configured, you can use AWS STS to create a temporary security credential for a collection on CASE-0001. You can use the AWS CLI to do this manually or you can write a script to automate this process using the AWS API. The IAM access key, secret access key, and session token returned by this call can then be used by any tool that can use AWS access keys to upload files into the specified S3 bucket.

The following example shows an AWS CLI call to AssumeRole using the example ForensicsUploadRole and a case named CASE-0001. The --duration-seconds parameter defines the period, in seconds, that the temporary credentials are valid; the default of 3600 seconds will provide temporary credentials that are valid for one hour.

$ aws sts assume-role \
	--role-arn arn:aws:iam::112233445566:role/ForensicsUploadRole \
	--role-session-name CASE-0001 \
	--duration-seconds 3600 \
	--policy '{"Version": "2012-10-17", "Statement": [{"Effect": "Allow", "Action": ["s3:PutObject", "s3:AbortMultipartUpload"], "Resource": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"}, {"Sid": "BasePermissionsForS3Upload", "Effect": "Allow", "Action": ["kms:GenerateDataKey", "kms:Encrypt", "kms:Decrypt"], "Resource": "*"}]}'

{
	"Credentials": {
		"AccessKeyId": "ASIAXXXX",
		"SecretAccessKey": "XXXX",
		"SessionToken": "XXXX",
		"Expiration": "2025-04-10T17:16:13+00:00"
	},
	"AssumedRoleUser": {
		"AssumedRoleId": "AROXXXX:CASE-0001",
		"Arn": "arn:aws:sts::112233445566:assumed-role/ForensicsUploadRole/CASE-0001"
	},
	"PackedPolicySize": 39
}

Now that you have obtained temporary credentials from AWS STS, you can use those credentials to upload a file into Amazon S3:

$ AWS_ACCESS_KEY_ID=ASIAXXXX \
	AWS_SECRET_ACCESS_KEY=XXXX \
	AWS_SESSION_TOKEN=XXXX \
	aws s3 cp evidence.zip s3://mycompany-forensics-collection/CASE-0001/evidence.zip

upload: evidence.zip to s3://mycompany-forensics-collection/CASE-0001/evidence.zip

You can also verify that you can’t use those credentials to upload a file into any other object prefixes or S3 buckets. For example, if you change CASE-0001 to CASE-0004 in the Amazon S3 upload command, you will receive an AccessDenied error because you’re trying to upload an object outside of the allowed key prefix.

$ AWS_ACCESS_KEY_ID=ASIAXXXX \
	AWS_SECRET_ACCESS_KEY=XXXX \
	AWS_SESSION_TOKEN=XXXX \
	aws s3 cp evidence.zip s3://mycompany-forensics-collection/CASE-0004/evidence.zip

upload failed: evidence.zip to s3://mycompany-forensics-collection/cases/CASE-0004/evidence.zip
An error occurred (AccessDenied) when calling the PutObject operation: User: arn:aws:sts::112233445566:assumed-role/ForensicsUploadRole/CASE-0001 is not authorized to perform: s3:PutObject on resource: "arn:aws:s3:::mycompany-forensics-collection/CASE-0004/evidence.zip" because no session policy allows the s3:PutObject action

Additionally, if you wait more than the lifetime of the token (1 hour in this case), attempting to upload a file into the bucket will fail, because the token will no longer be valid:

$ AWS_ACCESS_KEY_ID=ASIAXXXX \
	AWS_SECRET_ACCESS_KEY=XXXX \
	AWS_SESSION_TOKEN=XXXX \
	aws s3 cp evidence.zip s3://mycompany-forensics-collection/CASE-0001/evidence.zip

upload failed: evidence.zip to s3://mycompany-forensics-collection/CASE-0001/evidence.zip

An error occurred (ExpiredToken) when calling the PutObject operation: The provided token has expired.

Create an automated process to vend temporary credentials on demand

After you’ve verified the security benefits of creating temporary credentials for S3 uploads and validated that the credentials work with your forensic software of choice, you can now use them as part of an automated process.

A sample automated architecture is shown in Figure 3.

Figure 3: Architecture to automate S3 credential vending and forensic artifact collection.

Figure 3: Architecture to automate S3 credential vending and forensic artifact collection.

The workflow depicted in Figure 3 includes the following steps:

  1. The workflow is triggered by an alert from a detection source or a manual trigger from an incident responder.
  2. The workflow input is added to an Amazon Simple Queue Service (Amazon SQS) queue.
  3. The Amazon SQS queue invokes an AWS Lambda function which in turn executes a Step Functions state machine to orchestrate the workflow.
  4. First, the Step Functions workflow determines whether the target system is managed by AWS Systems Manager.
    1. If the target system isn’t managed by Systems Manager, an error is noted, and the execution is abandoned.
    2. If the target system is managed by Systems Manager, the Step Functions workflow determines the operating system (OS) of the target system and proceeds with the flow of execution.
  5. The workflow then continues by executing the Systems Manager documents that implement the forensic collection process:
    1. Downloads tooling:
      1. Generates dynamically scoped IAM temporary credentials that provide access to download the OS-specific tooling to be executed on the target system from the tooling S3 bucket. These credentials are tightly scoped to only allow downloads from the S3 prefix that corresponds to the tooling for the target system’s OS.
      2. Executes a Systems Manager command on the target system that uses the credentials generated from the previous step to download the OS tooling on the target system.
    2. Runs forensic tools:
      • Executes a Systems Manager command on the target system to execute the OS tooling on the target system.
  6. The Systems Manager commands run on the target system, which in this case is an EC2 instance.
  7. Results are uploaded to the evidence S3 bucket:
    1. Generates dynamically scoped IAM temporary credentials (as described previously) that provide access to upload the output of the previously executed tooling to the evidence S3 bucket. These credentials are tightly scoped to only allow uploads to a particular S3 prefix corresponding to the alert prefix.
    2. Executes a Systems Manager command on the target system to upload the output of the previously executed tooling to the evidence S3 bucket. After the upload is complete, it cleans up both the output and the evidence tooling from the target system.
    3. The evidence S3 bucket is tightly locked down to a subset of identities within the AWS security account. Access attempts from identities that aren’t allow listed trigger an Amazon EventBridge rule to alert the security team through an Amazon Simple Notification Service (Amazon SNS) topic.
  8. When the workflow is complete, related details and metrics are recorded in an Amazon DynamoDB table.
  9. The forensic analysis can be performed on a separate EC2 instance that has access to read from the evidence S3 bucket.

Deploying the example solution

You can use the AWS Cloud Development Kit (AWS CDK) repository to implement the architecture shown in Figure 3.

The AWS CDK solution is split into three stacks:

  1. SecurityStack: This stack contains the basic forensic artifact workflow orchestration infrastructure described in this post, including the Step Functions workflow, Lambda functions, AWS SQS queues, IAM roles, and S3 buckets.
  2. AlertStack: This stack contains the EventBridge workflow to notify administrators of anomalous activity in the evidence S3 bucket.
  3. CustomerStack: This stack contains the SSM documents that are executed for the forensic artifact workflow and an IAM role assumed by the SecurityStack when the workflow is invoked. It’s deployed into each child AWS account containing EC2 instances from which the security account is authorized to collect forensic artifacts.

Configuration

Before deploying the solution, there are several variables in the config.ts file that must be modified for the environment:

  1. SECURITY_ACCOUNT: Security Tooling AWS account ID.
  2. CUSTOMER_ACCOUNTS: Target AWS account IDs (the Child AWS account in the architecture diagram).
  3. ALERT_EMAIL_RECIPIENTS: List of email addresses that receive alerts when there is unexpected access to the evidence S3 bucket.
  4. ALLOW_LISTED_ROLE_NAMES: Roles allowed to access the evidence S3 bucket. Any other identities accessing the evidence S3 bucket will result in an alarm.

Deployment

After you’ve updated the config.ts file to reflect the account numbers, email recipients, and role names, the stacks can be deployed into your AWS infrastructure.

  1. Set Up AWS credentials using the AWS CLI:
    aws configure
  2. Install dependencies and configure constants:
    1. Clone the repository.
    2. Navigate to the project directory.
    3. Install project dependencies:
      npm install
    4. Configure constants in constants/config.ts with the required information:
      export const SECURITY_ACCOUNT = "123456789012"; // Your security tooling account ID 
      export const CUSTOMER_ACCOUNTS = ["234567890123", "345678901234"]; // Target account IDs 
      export const ALLOW_LISTED_ROLE_NAMES = ["SecurityAnalystRole"];// Roles allowed to access evidence S3 bucket 
      export const ALERT_EMAIL_RECIPIENTS = ["[email protected]"];// Email addresses for alerts

  3. Bootstrap AWS CDK in your accounts (if it hasn’t been done already):
    1. Example: cdk bootstrap aws://456789012345/us-east-1 (example security AWS account).
    2. Then bootstrap if necessary in any target AWS accounts.
  4. Deploy the AWS CDK Stacks:
    1. Synthesize the CloudFormation template:
      cdk synth
    2. Deploy the security and alert stacks in your security account:
      cdk deploy SecurityStack AlertStack
    3. Deploy the customer stacks in your workload accounts:
      cdk deploy CustomerStack-ACCOUNT_ID
  5. Set up your email alerts:
    1. After the AlertStack is deployed, it will email all addresses listed in ALERT_EMAIL_RECIPIENTS. Choose the embedded link to accept the AWS SNS topic in each of those accounts.

Testing

With deployment complete, it’s time to test the solution.

  1. Trigger an analysis
    1. Make sure you have a Linux EC2 instance running in one of your customer accounts and in the AWS Region where you deployed the preceding customer stack.
    2. Because this example uses Systems Manager to orchestrate the collection script, make sure that the EC2 instance is visible in Systems Manager either by checking the Systems Manager console, or by using the AWS CLI:
      1. Console: In the AWS Systems Manager console, choose Managed instances in the left navigation pane and verify your instance appears in the list. For more information, see Managed Instances in the AWS Systems Manager User Guide.
      2. AWS CLI: Run the following command to verify the instance is managed:
        aws ssm describe-instance-information --filters “Key=InstanceIds,Values=<instance-id>
        If the command returns instance information with PingStatus: Online, the instance is properly connected to Systems Manager.
    3. Post a message in your security account to the Amazon SQS queue to start the Step Functions workflow. Note that the values in angle brackets (for example <accountID>) are placeholders that you must update with relevant AWS account ID, tracking ticket ID, AWS Region, and EC2 instance ID values:
      aws sqs send-message --queue-url --message-body ‘{ “account”: “”, “ticket_id”: “”, “region”: “>”, “instance_id”: “” }’
  2. Go to the Step Functions console to view the successful execution of the workflow:
    Figure 4 – Workflow as shown in the Step Functions console

    Figure 4: Workflow as shown in the Step Functions console

  3. View the DynamoDB table to see the metadata for the results.
  4. Check the evidence S3 bucket to see the uploaded files from the forensic collection.

Conclusion

Collecting forensic artifacts securely is a critical component of any digital forensics investigation. This post demonstrated how to implement least privilege access controls and time-limited credentials for forensic evidence collection workflows that use Amazon S3 for artifact storage. By combining IAM session policies with AWS STS temporary credentials, you can provide forensic tools with secure, scoped-down access to upload artifacts without exposing long-lived credentials or granting overly permissive access.

The architecture presented in this post automates the process of generating temporary credentials, collecting forensic artifacts from both AWS and non-AWS resources, and securely storing them in S3 buckets with appropriate encryption, access controls, and audit logging. With this approach, your security teams can focus on analyzing evidence instead of managing credentials and permissions during active security incidents.To get started with this solution, deploy the example AWS CDK stacks provided in the collect forensic artifacts repository and customize them for your organization’s forensic investigation requirements. For more information about related AWS forensic investigation architectures, review the Automated Forensics Orchestrator for EC2 and How to build forensic kernel modules for Linux EC2 instances resources.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Jason Garman

Jason Garman

Jason is a principal security specialist solutions architect at AWS. He has 30 years of cybersecurity experience including incident response, reverse engineering, identity, and data protection. At AWS, he helps large organizations adopt the latest cloud and AI technologies while maintaining a high bar for data governance, security, and safety.

Vaishnav Murthy

Vaishnav Murthy

Vaishnav is a Senior Security Engineer with AWS CloudResponse. He has an extensive background in incident response and security automation and enjoys building automated solutions that help AWS customers investigate and respond to security incidents at scale.

Introducing workload simulation workbench for Amazon MSK Express broker

Post Syndicated from Manu Mishra original https://aws.amazon.com/blogs/big-data/introducing-workload-simulation-workbench-for-amazon-msk-express-broker/

Validating Kafka configurations before production deployment can be challenging. In this post, we introduce the workload simulation workbench for Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express Broker. The simulation workbench is a tool that you can use to safely validate your streaming configurations through realistic testing scenarios.

Solution overview

Varying message sizes, partition strategies, throughput requirements, and scaling patterns make it challenging for you to predict how your Apache Kafka configurations will perform in production. The traditional approaches to test these variables create significant barriers: ad-hoc testing lacks consistency, manual set up of temporary clusters is time-consuming and error-prone, production-like environments require dedicated infrastructure teams, and team training often happens in isolation without realistic scenarios. You need a structured way to test and validate these configurations safely before deployment. The workload simulation workbench for MSK Express Broker addresses these challenges by providing a configurable, infrastructure as code (IaC) solution using AWS Cloud Development Kit (AWS CDK) deployments for realistic Apache Kafka testing. The workbench supports configurable workload scenarios, and real-time performance insights.

Express brokers for MSK Provisioned make managing Apache Kafka more streamlined, more cost-effective to run at scale, and more elastic with the low latency that you expect. Each broker node can provide up to 3x more throughput per broker, scale up to 20x faster, and recover 90% quicker compared to standard Apache Kafka brokers. The workload simulation workbench for Amazon MSK Express broker facilitates systematic experimentation with consistent, repeatable results. You can use the workbench for multiple use cases like production capacity planning, progressive training to prepare developers for Apache Kafka operations with increasing complexity, and architecture validation to prove streaming designs and compare different approaches before making production commitments.

Architecture overview

The workbench creates an isolated Apache Kafka testing environment in your AWS account. It deploys a private subnet where consumer and producer applications run as containers, connects to a private MSK Express broker and monitors for performance metrics and visibility. This architecture mirrors the production deployment pattern for experimentation. The following image describes this architecture using AWS services.

MSK Workload SImulator WorkBench Architecture Diagram

This architecture is deployed using the following AWS services:

Amazon Elastic Container Service (Amazon ECS) generate configurable workloads with Java-based producers and consumers, simulating various real-world scenarios through different message sizes and throughput patterns.

Amazon MSK Express Cluster runs Apache Kafka 3.9.0 on Graviton-based instances with hands-free storage management and enhanced performance characteristics.

Dynamic Amazon CloudWatch Dashboards automatically adapt to your configuration, displaying real-time throughput, latency, and resource utilization across different test scenarios.

Secure Amazon Virtual Private Cloud (Amazon VPC) Infrastructure provides private subnets across three Availability Zones with VPC endpoints for secure service communication.

Configuration-driven testing

The workbench provides different configuration options for your Apache Kafka testing environment, so you can customize instance types, broker count, topic distribution, message characteristics, and ingress rate. You can adjust the number of topics, partitions per topic, sender and receiver service instances, and message sizes to match your testing needs. These flexible configurations support two distinct testing approaches to validate different aspects of your Kafka deployment:

Approach 1: Workload validation (single deployment)

Test different workload patterns against the same MSK Express cluster configuration. This is useful for comparing partition strategies, message sizes, and load patterns.

// Fixed MSK Express Cluster Configuration
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 1, // 1 broker per AZ = 3 total brokers
instanceType: 'express.m7g.large', // MSK Express instance type
};

// Multiple Concurrent Workload Tests
export const deploymentConfig: DeploymentConfig = { services: [
{ topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 1024 }, // High-throughput scenario
{ topics: 1, partitionsPerTopic: 3, instances: 1, messageSizeBytes: 512 }, // Latency-optimized scenario
{ topics: 3, partitionsPerTopic: 4, instances: 2, messageSizeBytes: 4096 }, // Multi-topic scenario
]};

Approach 2: Infrastructure rightsizing (redeploy and compare)

Test different MSK Express cluster configurations by redeploying the workbench with different broker settings while keeping the same workload. This is recommended for rightsizing experiments and understanding the impact of vertical compared to horizontal scaling.

// Baseline: Deploy and test
export const mskBrokerConfig: MskBrokerConfig = { numberOfBrokers: 1, instanceType: 'express.m7g.large',};

// Vertical scaling: Redeploy with larger instances
export const mskBrokerConfig: MskBrokerConfig = { numberOfBrokers: 1,
instanceType: 'express.m7g.xlarge', // Larger instances
};

// Horizontal scaling: Redeploy with more brokers
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 2, // More brokers
instanceType: 'express.m7g.large',};

Each redeployment uses the same workload configuration, so you can isolate the impact of infrastructure changes on performance.

Workload testing scenarios (single deployment)

These scenarios test different workload patterns against the same MSK Express cluster:

Partition strategy impact testing

Scenario: You are debating the usage of fewer topics with many partitions compared to many topics with fewer partitions for your microservices architecture. You want to understand how partition count affects throughput and consumer group coordination before making this architectural decision.

const deploymentConfig = { services: [
{ topics: 1, partitionsPerTopic: 1, instances: 2, messageSizeBytes: 1024 }, // Baseline: minimal partitions
{ topics: 1, partitionsPerTopic: 10, instances: 2, messageSizeBytes: 1024 }, // Medium partitions
{ topics: 1, partitionsPerTopic: 20, instances: 2, messageSizeBytes: 1024 }, // High partitions
]};

Message size performance analysis

Scenario: Your application handles different types of events – small IoT sensor readings (256 bytes), medium user activity events (1 KB), and large document processing events (8KB). You must understand how message size impacts your overall system performance and if you should separate these into different topics or handle them together.

const deploymentConfig = { services: [
{ topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 256 }, // IoT sensor data
{ topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 1024 }, // User events
{ topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 8192 }, // Document events
]};

Load testing and scaling validation

Scenario: You expect traffic to vary significantly throughout the day, with peak loads requiring 10× more processing capacity than off-peak hours. You want to validate how your Apache Kafka topics and partitions handle different load levels and understand the performance characteristics before production deployment.

const deploymentConfig = { services: [
{ topics: 2, partitionsPerTopic: 6, instances: 1, messageSizeBytes: 1024 }, // Off-peak load simulation
{ topics: 2, partitionsPerTopic: 6, instances: 5, messageSizeBytes: 1024 }, // Medium load simulation
{ topics: 2, partitionsPerTopic: 6, instances: 10, messageSizeBytes: 1024 }, // Peak load simulation
]};

Infrastructure rightsizing experiments (redeploy and compare)

These scenarios help you understand the impact of different MSK Express cluster configurations by redeploying the workbench with different broker settings:

MSK broker rightsizing analysis

Scenario: You deploy a cluster with basic configuration and put load on it to establish baseline performance. Then you want to experiment with different broker configurations to see the effect of vertical scaling (larger instances) and horizontal scaling (more brokers) to find the right cost-performance balance for your production deployment.

Step 1: Deploy with baseline configuration

// Initial deployment: Basic configuration
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 1, // 3 total brokers (1 per AZ)
instanceType: 'express.m7g.large',};export const deploymentConfig: DeploymentConfig = { services: [ { topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 1024 }, ]};

Step 2: Redeploy with vertical scaling

// Redeploy: Test vertical scaling impact
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 1, // Same broker count
instanceType: 'express.m7g.xlarge', // Larger instances
};

// Keep same workload configuration to compare results

Step 3: Redeploy with horizontal scaling

// Redeploy: Test horizontal scaling impact
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 2, // 6 total brokers (2 per AZ)
instanceType: 'express.m7g.large', // Back to original size
};

// Keep same workload configuration to compare results

This rightsizing approach helps you understand how broker configuration changes affect the same workload, so you can improve both performance and cost for your specific requirements.

Performance insights

The workbench provides detailed insights into your Apache Kafka configurations through monitoring and analytics, creating a CloudWatch dashboard that adapts to your configuration. The dashboard starts with a configuration summary showing your MSK Express cluster details and workbench service configurations, helping you to understand what you’re testing. The following image shows the dashboard configuration summary:

The second section of dashboard shows real-time MSK Express cluster metrics including:

  • Broker performance: CPU utilization and memory usage across brokers in your cluster
  • Network activity: Monitor bytes in/out and packet counts per broker to understand network utilization patterns
  • Connection monitoring: Displays active connections and connection patterns to help identify potential bottlenecks
  • Resource utilization: Broker-level resource tracking provides insights into overall cluster health

The following image shows the MSK cluster monitoring dashboard:

The third section of the dashboard shows the Intelligent Rebalancing and Cluster Capacity insights showing:

  • Intelligent rebalancing: in progress: Shows whether a rebalancing operation is currently in progress or has occurred in the past. A value of 1 indicates that rebalancing is actively running, while 0 means that the cluster is in a steady state.
  • Cluster under-provisioned: Indicates whether the cluster has insufficient broker capacity to perform partition rebalancing. A value of 1 means that the cluster is under-provisioned and Intelligent Rebalancing can’t redistribute partitions until more brokers are added or the instance type is upgraded.
  • Global partition count: Displays the total number of unique partitions across all topics in the cluster, excluding replicas. Use this to track partition growth over time and validate your deployment configuration.
  • Leader count per broker: Shows the number of leader partitions assigned to each broker. An uneven distribution indicates partition leadership skew, which can lead to hotspots where certain brokers handle disproportionate read/write traffic.
  • Partition count per broker: Shows the total number of partition replicas hosted on each broker. This metric includes both leader and follower replicas and is key to identifying replica distribution imbalances across the cluster.

The following image shows the Intelligent Rebalancing and Cluster Capacity section of the dashboard:

The fourth section of the dashboard shows the application-level insights showing:

  • System throughput: Displays the total number of messages per second across services, giving you a complete view of system performance
  • Service comparisons: Performs side-by-side performance analysis of different configurations to understand which approaches fit
  • Individual service performance: Each configured service has dedicated throughput tracking widgets for detailed analysis
  • Latency analysis: The end-to-end message delivery times and latency comparisons across different service configurations
  • Message size impact: Performance analysis across different payload sizes helps you understand how message size affects overall system behavior

The following image shows the application performance metrics section of the dashboard:

Getting started

This section walks you through setting up and deploying the workbench in your AWS environment. You will configure the necessary prerequisites, deploy the infrastructure using AWS CDK, and customize your first test.

Prerequisites

You can deploy the solution from the GitHub Repo. You can clone it and run it on your AWS environment. To deploy the artifacts, you will require:

  • AWS account with administrative credentials configured for creating AWS resources.
  • AWS Command Line Interface (AWS CLI) must be configured with appropriate permissions for AWS resource management.
  • AWS Cloud Development Kit (AWS CDK) should be installed globally using npm install -g aws-cdk for infrastructure deployment.
  • Node.js version 20.9 or higher is required, with version 22+ recommended.
  • Docker engine must be installed and running locally as the CDK builds container images during deployment. Docker daemon should be running and accessible to CDK for building the workbench application containers.

Deployment

# Clone the workbench repository
git clone https://github.com/aws-samples/sample-simulation-workbench-for-msk-express-brokers.git

# Install dependencies and build
npm install 
npm run build

# Bootstrap CDK (first time only per account/region)
cd cdk 
npx cdk bootstrap

# Synthesize CloudFormation template (optional verification step)
npx cdk synth

# Deploy to AWS (creates infrastructure and builds containers)
npx cdk deploy

After deployment is completed, you will receive a CloudWatch dashboard URL to monitor the workbench performance in real-time.You can also deploy multiple isolated instances of the workbench in the same AWS account for different teams, environments, or testing scenarios. Each instance operates independently with its own MSK cluster, ECS services, and CloudWatch dashboards.To deploy additional instances, modify the Environment Configuration in cdk/lib/config.ts:

// Instance 1: Development team
export const AppPrefix = 'mske';export const EnvPrefix = 'dev';

// Instance 2: Staging environment (separate deployment)
export const AppPrefix = 'mske';export const EnvPrefix = 'staging';

// Instance 3: Team-specific testing (separate deployment)
export const AppPrefix = 'team-alpha';export const EnvPrefix = 'test';

Each combination of AppPrefix and EnvPrefix creates completely isolated AWS resources so that multiple teams or environments can use the workbench simultaneously without conflicts.

Customizing your first test

You can edit the configuration file located at folder “cdk/lib/config-types.ts” to define your testing scenarios and run the deployment. It is preconfigured with the following configuration:

export const deploymentConfig: DeploymentConfig = { services: [
// Start with a simple baseline test
{ topics: 1, partitionsPerTopic: 3, instances: 1, messageSizeBytes: 1024 },

// Add a comparison scenario
{ topics: 1, partitionsPerTopic: 6, instances: 1, messageSizeBytes: 1024 }, ]};

Best practices

Following a structured approach to benchmarking ensures that your results are reliable and actionable. These best practices will help you isolate performance variables and build a clear understanding of how each configuration change affects your system’s behavior. Begin with single-service configurations to establish baseline performance:

const deploymentConfig = { services: [ { topics: 1, partitionsPerTopic: 3, instances: 1, messageSizeBytes: 1024 } ]};

After you understand the baseline, add comparison scenarios.

Change one variable at a time

For clear insights, modify only one parameter between services:

const deploymentConfig = { services: [
{ topics: 1, partitionsPerTopic: 3, instances: 1, messageSizeBytes: 1024 }, // Baseline
{ topics: 1, partitionsPerTopic: 6, instances: 1, messageSizeBytes: 1024 }, // More partitions
{ topics: 1, partitionsPerTopic: 12, instances: 1, messageSizeBytes: 1024 }, // Even more partitions
]};

This approach helps you understand the impact of specific configuration changes.

Important considerations and limitations

Before relying on workbench results for production decisions, it is important to understand the tool’s intended scope and boundaries. The following considerations will help you set appropriate expectations and make the most effective use of the workbench in your planning process.

Performance testing disclaimer

The workbench is designed as an educational and sizing estimation tool to help teams prepare for MSK Express production deployments. While it provides valuable insights into performance characteristics:

  • Results can vary based on your specific use cases, network conditions, and configurations
  • Use workbench results as guidance for initial sizing and planning
  • Conduct comprehensive performance validation with your actual workloads in production-like environments before final deployment

Recommended usage approach

Production readiness training – Use the workbench to prepare teams for MSK Express capabilities and operations.

Architecture validation – Test streaming architectures and performance expectations using MSK Express enhanced performance characteristics.

Capacity planning – Use MSK Express streamlined sizing approach (throughput-based rather than storage-based) for initial estimates.

Team preparation – Build confidence and expertise with production Apache Kafka implementations using MSK Express.

Conclusion

In this post, we showed how the workload simulation workbench for Amazon MSK Express Broker supports learning and preparation for production deployments through configurable, hands-on testing and experiments. You can use the workbench to validate configurations, build expertise, and improve performance before production deployment. If you’re preparing for your first Apache Kafka deployment, training a team, or improving existing architectures, the workbench provides practical experience and insights needed for success. Refer to Amazon MSK documentation – Complete MSK Express documentation, best practices, and sizing guidance for more information.


About the authors

Manu MishraManu Mishra is a Senior Solutions Architect at AWS with over 18 years of experience in the software industry, specializing in artificial intelligence, data and analytics, and security. His expertise spans strategic oversight and hands-on technical leadership, where he reviews and guides the work of both internal and external customers. Manu collaborates with AWS customers to shape technical strategies that drive impactful business outcomes, providing alignment between technology and organizational goals.

Manu Mishra Ramesh Chidirala is a Senior Solutions Architect at Amazon Web Services with over two decades of technology leadership experience in architecture and digital transformation, helping customers align business strategy and technical execution. He specializes in designing innovative, AI-powered, cost-efficient serverless event-driven architectures and has extensive experience architecting secure, scalable, and resilient cloud solutions for enterprise customers.

Proactive monitoring for Amazon Redshift Serverless using AWS Lambda and Slack alerts

Post Syndicated from Cristian Restrepo Lopez original https://aws.amazon.com/blogs/big-data/proactive-monitoring-for-amazon-redshift-serverless-using-aws-lambda-and-slack-alerts/

Performance issues in analytics environments often remain invisible until they disrupt dashboards, delay ETL jobs, or impact business decisions. For teams running Amazon Redshift Serverless, unmonitored query queues, long-running queries, or unexpected spikes in compute capacity can degrade performance and increase costs if left undetected.

Amazon Redshift Serverless streamlines running analytics at scale by removing the need to provision or manage infrastructure. However, even in a serverless environment, maintaining visibility into performance and usage is essential for efficient operation and predictable costs. While Amazon Redshift Serverless provides advanced built-in dashboards for monitoring performance metrics, delivering notifications directly to platforms like Slack, brings another level of agility. Real-time alerts in the team’s workflow enable faster response times and more informed decision-making without requiring constant dashboard monitoring.

In this post, we show you how to build a serverless, low-cost monitoring solution for Amazon Redshift Serverless that proactively detects performance anomalies and sends actionable alerts directly to your selected Slack channels. This approach helps your analytics team identify and address issues early, often before your users notice a problem.

Solution overview

The solution presented in this post uses AWS services to collect key performance metrics from Amazon Redshift Serverless, evaluate them against thresholds that you can flexibly configure, and notify you when anomalies are detected.

scope of solution

The workflow operates as follows:

  1. Scheduled execution – An Amazon EventBridge rule triggers an AWS Lambda function on a configurable schedule (by default, every 15 minutes during business hours).
  2. Metric collection – The AWS Lambda function gathers metrics including queued queries, running queries, compute capacity (RPUs), data storage usage, table count, database connections, and slow-running queries using Amazon CloudWatch and the Amazon Redshift Data API.
  3. Threshold evaluation – Collected metrics are compared against your predefined thresholds that reflect acceptable performance and usage limits.
  4. Alerting – When a threshold is exceeded, the Lambda function publishes a notification to an Amazon SNS topic.
  5. Slack notification – Amazon Q Developer in Chat applications (formerly AWS Chatbot) delivers the alert to your designated Slack channel.
  6. Observability – Lambda execution logs are stored in Amazon CloudWatch Logs for troubleshooting and auditing.

This architecture is fully serverless and requires no changes to your existing Amazon Redshift Serverless workloads. To simplify deployment, we provide an AWS CloudFormation template that provisions all required resources.

Prerequisites

Before deploying this solution, you must collect information about your existing Amazon Redshift Serverless workgroup and namespace that you want to monitor. To identify your Amazon Redshift Serverless resources:

  1. Open the Amazon Redshift console.
  2. In the navigation pane, choose Serverless dashboard.
  3. Note down your workgroup and namespace names. You will use these values when launching this blog’s AWS CloudFormation template.

Deploy the solution

You can launch the CloudFormation stack and deploy the solution via the provided link.

GitHub Repo

When launching the CloudFormation stack, complete the following steps in the AWS CloudFormation Console:

  1. For Stack name, enter a descriptive name such as redshift-serverless-monitoring.
  2. Review and modify the parameters as needed for your environment.
  3. Acknowledge that AWS CloudFormation may create IAM resources with custom names.
  4. Choose Submit.

CloudFormation parameters

Amazon Redshift Serverless Workgroup configuration

Provide details for your existing Amazon Redshift Serverless environment. These values connect the monitoring solution to your Redshift environment. Some parameters come with the default values that you can replace with your actual configuration.

Parameter Default value Description
Amazon Redshift Workgroup Name Your Amazon Redshift Serverless workgroup name.
Amazon Redshift Namespace Name Your Amazon Redshift Serverless namespace name.
Amazon Redshift Workgroup ID Workgroup ID (UUID) of the Amazon Redshift Serverless workgroup to monitor. Must follow the UUID format: xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx (lowercase hexadecimal with hyphens).
Namespace ID (UUID) of the Amazon Redshift Serverless namespace. Must follow the UUID format: xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx (lowercase hexadecimal with hyphens).
Database Name dev Target Amazon Redshift database for SQL-based diagnostic and monitoring queries.

Monitoring schedule

The default schedule runs diagnostic SQL queries every 15 minutes during business hours, balancing responsiveness and cost efficiency. Running more frequently might increase costs, while less frequent monitoring could delay detection of performance issues. You can adjust this schedule to your actual need.

Parameter Default value Description
Schedule Expression cron(0/15 8-17 ? * MON-FRI *) EventBridge schedule expression for Lambda function execution. Default runs every 15 minutes, Monday through Friday, 8 AM to 5 PM UTC.

Threshold configuration

Thresholds should be tuned based on your workload characteristics.

Parameter Default value Description
Queries Queued Threshold 20 Alerts threshold for queued queries.
Queries Running Threshold 20 Alerts threshold for running queries.
Compute Capacity Threshold (RPUs) 64 Alert threshold for compute capacity (RPUs).
Data Storage Threshold (MB) 5242880 Threshold for data storage in MB (default 5 TB).
Table Count Threshold (MB) 1000 Alerts threshold for total table count.
Database Connections Threshold 50 Alert threshold for database connections.
Slow Query Threshold (seconds) 10 Thresholds in seconds for slow query detection.
Query Timeout (Seconds) 30 Timeout for SQL diagnostics queries.

Tip: Start with conservative thresholds and refine them after observing baseline behavior for one to two weeks.

Lambda configuration

Configure the AWS Lambda function settings. The selected default values are appropriate for most monitoring scenarios. You may want to change them only in case of troubleshooting.

Parameter Default value Description
Lambda Memory Size (MB) 256 Lambda function memory size in MB.
Lambda Time Out (Seconds) 240 Lambda function timeout in seconds.

Security Configuration – Amazon Virtual Private Cloud (VPC)

If your organization has network isolation requirements, you can optionally enable VPC deployment for the Lambda function. When enabled, the Lambda function runs within your specified VPC subnets, providing network isolation and allowing access to VPC-only resources.

Parameter Default value Description
VPC ID VPC ID for Lambda deployment (required if EnableVPC is true). The Lambda function will be deployed in this VPC. Ensure that the VPC has appropriate routing (NAT Gateway or VPC Endpoints) to allow Lambda to access AWS services like CloudWatch, Amazon Redshift, and Amazon SNS.
VPC Subnet IDs Comma-separated list of subnet IDs for Lambda deployment (required if EnableVPC is true).
Security Group IDs Comma-separated list of security group IDs for Lambda (optional). If not provided and EnableVPC is true, a default security group will be created with outbound HTTPS access. Custom security groups must allow outbound HTTPS (port 443) to AWS service endpoints.

Note that VPC deployment might increase cold start times and requires an NAT Gateway or VPC endpoints for AWS service access. We recommend provisioning interface VPC endpoints (through AWS PrivateLink) for the five services the Lambda function calls which keeps all traffic private without the recurring cost of a NAT Gateway.

Security configuration – Encryption

If your organization requires encryption of data at rest, you can optionally enable AWS Key Management Service (AWS KMS) encryption for the Lambda function’s environment variables, CloudWatch Logs, and SNS topic. When enabled, the template encrypts each resource using the AWS KMS keys that you provide, either a single shared key for all three services, or individual keys for granular key management and audit separation.

Parameter Default value Description
Shared KMS Key ARN AWS KMS key ARN to use for all encryption (Lambda, Logs, and SNS) unless service-specific keys are provided. This streamlines key management by using a single key for all services. The key policy must grant encrypt/decrypt permissions to Lambda, CloudWatch Logs, and SNS.
Lambda KMS Key ARN AWS KMS key ARN for Lambda environment variable encryption (optional, overrides SharedKMSKeyArn). Use this for separate key management per service. The key policy must grant decrypt permissions to the Lambda execution role. If not provided, SharedKMSKeyArn will be used when EnableKMSEncryption is true.
CloudWatch Logs KMS Key ARN AWS KMS key ARN for CloudWatch Logs encryption (optional, overrides SharedKMSKeyArn). Use this for separate key management per service. The key policy must grant encrypt/decrypt permissions to the CloudWatch Logs service. If not provided, SharedKMSKeyArn will be used when EnableKMSEncryption is true.
SNS Topic KMS Key ARN AWS KMS key ARN for SNS topic encryption (optional, overrides SharedKMSKeyArn). Use this for separate key management per service. The key policy must grant encrypt/decrypt permissions to SNS service and the Lambda execution role. If not provided, SharedKMSKeyArn will be used when EnableKMSEncryption is true.
Enable Dead Letter Queue False Optionally enable Dead Letter Queue (DLQ) for failed Lambda invocations to improve reliability and security monitoring. When enabled, events that fail after all retry attempts will be sent to an SQS queue for investigation and potential replay. This helps prevent data loss, provides visibility into failures, and enables security audit trails for monitoring anomalies. The DLQ retains messages for 14 days.

Note that AWS KMS encryption requires the key policy to grant appropriate permissions to each consuming service (Lambda, CloudWatch Logs, and SNS).

  1. On the review page, select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  2. Choose Submit.

Resources created

The CloudFormation stack creates the following resources:

  • EventBridge rule for scheduled execution
  • AWS Lambda function (Python 3.12 runtime)
  • Amazon SNS topic for alerts
  • IAM role with permissions for CloudWatch, Amazon Redshift Data API, and SNS
  • CloudWatch Log Group for Lambda logs

Note: CloudFormation deployment typically takes 10–15 minutes to complete. You can monitor progress in real time under the Events tab of your CloudFormation stack.

Post-deployment configuration

After the CloudFormation stack has been successfully created, complete the following steps.

Step 1: Record CloudFormation outputs

  1. Navigate to the AWS CloudFormation console.
  2. Select your stack and choose the Outputs tab.
  3. Note the values for LambdaRoleArn and SNSTopicArn. You will need these in subsequent steps.

Step 2: Grant Amazon Redshift permissions

Grant permissions to the Lambda function to query Amazon Redshift system tables for monitoring data. Complete the following steps to grant the necessary access:

  1. Navigate to the Amazon Redshift console.
  2. In the left navigation pane, choose Query Editor V2.
  3. Connect to your Amazon Redshift Serverless workgroup.
  4. Execute the following SQL commands, replacing <IAM Role ARN> with the LambdaRoleArn value from your CloudFormation outputs:
CREATE USER "IAMR:<IAM Lambda Role>" WITH PASSWORD DISABLE;

GRANT ROLE "sys:monitor" TO "IAMR:<IAM Role>";

RedshiftSQL-DBD-5612

These commands create an AmazonRedshift user associated with the Lambda IAM role and grant it the sys:monitor Amazon Redshift role. This role provides read-only access to catalog and system tables without granting permissions to user data tables.

Step 3: Configure Slack notifications

Amazon Q Developer in chat applications provides native AWS integration and managed authentication, removing custom webhook code and reducing setup complexity. To receive alerts in Slack, configure Amazon Q Developer in Chat Applications to connect your SNS topic to your preferred Slack channel:

  1. Navigate to Amazon Q Developer in chat applications (formerly AWS Chatbot) in the AWS console.
  2. Follow the instructions in the Slack integration documentation to authorize AWS access to your Slack workspace.
  3. When configuring the Slack channel, ensure that you select the correct AWS Region where you deployed the CloudFormation stack.
  4. In the Notifications section, select the SNS topic created by your CloudFormation stack (refer to the SNSTopicArn output value).
  5. Keep the default IAM read-only permissions for the channel configuration.

SNS topic

After configured, alerts automatically appear in Slack whenever thresholds are exceeded.

result-upon-success

Cost considerations

With the default configuration, this solution incurs minimal ongoing costs. The Lambda function executes approximately 693 times per month (every 15 minutes during an 8-hour business day, Monday through Friday), resulting in a monthly cost of approximately $0.33 USD. This includes Lambda compute costs ($0.26) and CloudWatch GetMetricData API calls ($0.07). All other services (EventBridge, SNS, CloudWatch Logs, and Amazon Redshift Data API). The Amazon Redshift Data API has no additional charges beyond the minimal Amazon Redshift Serverless RPU consumption for the Amazon Redshift Serverless system table query execution. You can reduce costs by decreasing the monitoring frequency (such as, every 30 minutes) or increase responsiveness by running more frequently (such as, every 5 minutes) with a proportional cost increase.

All costs are estimates and may vary based on your environment. Variations often occur because queries scanning system tables may take longer or require additional resources depending on the system complexity

Security best practices

This solution implements the following security controls:

  • IAM policies scoped to specific resource ARNs for the Amazon Redshift workgroup, namespace, SNS topic, and log group.
  • Data API statement access restricted to the Lambda function’s own IAM user ID.
  • Read-only sys:monitor database role for operational metadata access. Limit to the role created by the CloudFormation template.
  • Reserved concurrent executions capped at five.

To further strengthen your security posture, consider the following enhancements:

  • Enable EnableKMSEncryption to encrypt environment variables, logs, and SNS messages at rest.
  • Enable EnableVPC to deploy the function within a VPC for network isolation.
  • Audit access through AWS CloudTrail.

Important: This is sample code for non-production usage. Work with your security and legal teams to meet your organizational security, regulatory, and compliance requirements before deployment. This solution demonstrates monitoring capabilities but requires additional security hardening for production environments, including encryption configuration, IAM policy scoping, VPC deployment, and comprehensive testing.

Clean up

To remove all resources and avoid ongoing charges if you don’t want to use the solution anymore:

  1. Delete the CloudFormation stack.
  2. Remove the Slack integration from Amazon Q Developer in chat applications.

Troubleshooting

  • If no metrics or incomplete SQL diagnostics are returned, verify that the Amazon Redshift Serverless workgroup is active with recent query activity, and ensure the database user has the sys:monitor role (GRANT ROLE sys:monitor TO <user>) in the query editor. Without this role, queries execute successfully but only return data visible to that user’s permissions rather than the full cluster activity.
  • For VPC-deployed functions that fail to reach AWS services, confirm that VPC endpoints or a NAT Gateway are configured for CloudWatch, Amazon Redshift Data API, Amazon Redshift Serverless, SNS, and CloudWatch Logs.
  • If the Lambda function times out, increase the LambdaTimeout and QueryTimeoutSeconds parameters. The default timeout of 240 seconds accommodates most workloads, but clusters with many active queries may require additional time for SQL diagnostics to complete.

Conclusion

In this post, we showed how you can build a proactive monitoring solution for Amazon Redshift Serverless using AWS Lambda, Amazon CloudWatch, and Amazon SNS with Slack integration. By automatically collecting metrics, evaluating thresholds, and delivering alerts in near real time to Slack or your preferred collaborative platform, this solution helps detect performance and cost issues early. Because the solution itself is serverless, it aligns with the operational simplicity goals of Amazon Redshift Serverless—scaling automatically, requiring minimal maintenance, and delivering high value at low cost. You can extend this foundation with additional metrics, diagnostic logic, or alternative notification channels to meet your organization’s needs.

To learn more, see the Amazon Redshift documentation on monitoring and performance optimization.


About the authors

Headhost author 1

Cristian Restrepo Lopez

Cristian is a Solutions Architect at AWS, helping customers build modern data applications with a focus on analytics. Outside of work, he enjoys exploring emerging technologies and connecting with the data community.

Satesh Sonti

Satesh is a Principal Analytics Specialist Solutions Architect based out of Atlanta, specializing in building enterprise data platforms, data warehousing, and analytics solutions. He has over 19 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

Modernize business intelligence workloads using Amazon Quick

Post Syndicated from Satesh Sonti original https://aws.amazon.com/blogs/big-data/modernize-business-intelligence-workloads-using-amazon-quick/

Traditional business intelligence (BI) integration with enterprise data warehouses has been the established pattern for years. With generative AI, you can now modernize BI workloads with capabilities like interactive chat agents, automated business processes, and using natural language to generate dashboards.

In this post, we provide implementation guidance for building integrated analytics solutions that combine the generative BI features of Amazon Quick with Amazon Redshift and Amazon Athena SQL analytics capabilities. Use this post as a reference for proof-of-concept implementations, production deployment planning, or as a learning resource for understanding Quick integration patterns with Amazon Redshift and Athena.

Common use cases

You can use this integrated approach across several scenarios. The following are some of the most common use cases.

  • Traditional BI reporting benefits from bundled data warehouse and BI tool pricing, making generative BI the primary use case with significant cost advantages.
    • Insurance: Automates Solvency II and IFRS 17 regulatory reporting, replacing manual spreadsheet consolidation.
    • Banking: Accelerates FDIC call report generation and capital adequacy dashboards, cutting month-end close from days to hours.
  • Interactive dashboards with contextual chat agents give BI teams conversational interfaces alongside their visual metrics.
    • Gaming: Live ops teams query player retention and monetization KPIs in plain English—no SQL needed.
    • Financial Services: Trading analysts chat with real-time P&L dashboards to surface anomalies and drill into positions on demand.
  • Domain-specific analytics workspaces democratize enterprise data exploration through Quick Spaces and natural language queries.
    • Insurance: Actuarial and underwriting teams query claims and risk data without waiting on data engineering.
    • Banking: Risk and compliance teams explore credit, market, and operational data through a single natural language interface.
  • Workflow automation removes repetitive tasks and accelerates self-service analytics.
    • Financial Services: Automated AR reconciliation flows replace manual ledger matching, shrinking close cycle effort significantly.
    • Gaming: Telemetry ingestion pipelines trigger reporting refreshes automatically, freeing data engineers from routine work.

Let us examine an end-to-end solution combining these technologies.

Solution flow

AWS offers two native SQL analytics engines for building analytics workloads. Amazon Redshift provides a fully managed data warehouse with columnar storage and massively parallel processing. Amazon Athena delivers serverless interactive query capabilities directly against data in Amazon S3.

You can use either Amazon Redshift or Amazon Athena as a SQL engine while implementing the steps in this post. The following are the steps involved in building an end-to-end solution.

Solution steps to integrate SQL Analytics engines with Amazon Quick

Figure1: Solution steps to integrate SQL Analytics engines with Amazon Quick

  1. Set up your SQL analytics engines: Amazon Redshift or Amazon Athena.
  2. Load data and create business views designed for analytics workloads.
  3. Configure integration between SQL analytics engines and Amazon Quick.
  4. Create data sources in Amazon Quick.
  5. Create datasets and dashboards for visual analytics.
  6. Use Topics and Spaces to provide natural language interfaces to your data.
  7. Deploy chat agents to deliver conversational AI experiences for business users.
  8. Implement business flows to automate repetitive workflows and processes.

Let’s start by walking through steps 1–4 for Amazon Redshift. We then describe the same four steps for Amazon Athena before explaining the Amazon Quick steps 5–8.

Configure and create datasets in Amazon Redshift

Amazon Redshift offers two deployment options to meet your data warehousing needs. Provisioned clusters provide traditional deployment where you manage compute resources by selecting node types and cluster size. Serverless automatically scales compute capacity based on workload demands with pay-per-use pricing. Both options are supported by Amazon Quick. For this walkthrough, we use Redshift Serverless.

Set up SQL analytics engine

To create a Redshift Serverless namespace and workgroup:

  1. Open the Amazon Redshift console.
  2. On the left navigation pane, select Redshift Serverless.
  3. Follow the steps described in the Creating a workgroup with a namespace documentation page to create a workgroup and a namespace. Note the username and password provided. You will use these details for configuring connections in Amazon Redshift and Quick.
  4. You should see the status as Available for both the workgroup and namespace in the Serverless dashboard.

Amazon Redshift Serverless Workgroup and Namespaces

Figure 2: Amazon Redshift Serverless Workgroup and NamespacesThe deployment will be completed in approximately 3–5 minutes.

Load data and create business views

Now you can load data using the industry-standard TPC-H benchmark dataset, which provides realistic customer, order, and product data for analytics workloads.To load data into Amazon Redshift:

  1. Open the Amazon Redshift Query Editor V2 from the console.
  2. Run the TPC H DDL statements to create TPC-H tables.
  3. Run the following COPY commands to load data from the public S3 bucket: s3://redshift-downloads/TPC-H/.

Ensure that the IAM role attached to the namespace is set as the default IAM role. If you didn’t set up the default IAM role at the time of namespace creation, you can refer to the Creating an IAM role as default for Amazon Redshift documentation page to set it now.

copy customer from 's3://redshift-downloads/TPC-H/2.18/100GB/customer/' iam_role default delimiter '|' region 'us-east-1'; 

copy orders from 's3://redshift-downloads/TPC-H/2.18/100GB/orders/' iam_role default delimiter '|' region 'us-east-1'; 

copy lineitem from 's3://redshift-downloads/TPC-H/2.18/100GB/lineitem/' iam_role default delimiter '|' region 'us-east-1'; 

Run the following query to validate load status. The status column should show as completed. You can also review the information in other columns to see details about the loads such as record counts, duration, and data source.
select * from  SYS_LOAD_HISTORY  Where table_name in ('customer','orders','lineitem');

Output of SYS_LOAD_HISTORY showing successful completion of COPY Jobs
Figure 3: Output of SYS_LOAD_HISTORY showing successful completion of COPY Jobs

  1. Create a materialized view to improve query performance:

Run the following SQL to create a materialized view that pre-compute results set for customer revenues and order volumes by market segment.

CREATE MATERIALIZED VIEW mv_customer_revenue AS 
SELECT 
c.c_custkey, 
c.c_name, 
c.c_mktsegment, 
SUM(l.l_extendedprice * (1 - l.l_discount)) as total_revenue, 
COUNT(DISTINCT o.o_orderkey) as order_count 
FROM customer c 
JOIN orders o ON c.c_custkey = o.o_custkey
JOIN lineitem l ON o.o_orderkey = l.l_orderkey
GROUP BY c.c_custkey, c.c_name, c.c_mktsegment;

Run the following SQL to review the data in the materialized view.

select * from mv_customer_revenue limit 10;

Configure integration with Amazon Quick

Amazon Quick auto discovers the Amazon Redshift provisioned clusters that are associated with your AWS account. These resources must be in the same AWS Region as your Amazon Quick account. For Amazon Redshift clusters in other accounts or Amazon Redshift Serverless, we recommend that you add a VPC connection following the steps in Enabling access to an Amazon Redshift cluster in a VPC documentation. Usually, these steps are performed by your organization’s cloud security administration team.

For serverless, you will apply the same steps in the workgroup instead of the cluster. You can find the VPC and Security Group settings in the Data Access tab of a workgroup.

Amazon Redshift Serverless workgroup VPC and Security groups
Figure 4: Amazon Redshift Serverless workgroup VPC and Security groups

You can also refer to How do I privately connect Quick to an Amazon Redshift or RDS data source in a private subnet? for a demonstration.

Create data source

To create a dataset connecting to Amazon Redshift, complete the following steps.

  1. In the Quick left navigation pane, go to Datasets.
  2. Choose the Data sources tab and select Create data source.
  3. Select Amazon Redshift and enter the following:
    • Data Source Name: Provide customer-rev-datasource as data source name.
    • Connection type: Select the VPC connection created in the previous step.
    • Database server: Enter the Amazon Redshift workgroup endpoint (for example, quick-demo-wg.123456789.us-west-2.redshift-serverless.amazonaws.com).
    • Port: 5439 (default).
    • Database: dev.
    • Username/Password: Amazon Redshift credentials with access to the database.
  4. Choose Validate connection. The validation should be successful.

Amazon Redshift data source configuration
Figure 5: Amazon Redshift data source configuration

  1. Choose Create Data Source to create a data source.

Now let’s explore how to perform all these four steps to configure Athena in Amazon Quick.

Configure and create datasets in Amazon Athena

Amazon Athena provides immediate query capabilities against petabytes of data with automatic scaling to handle concurrent users. Let’s go through the steps to configure connections between Amazon Quick and Amazon Athena.

Set up SQL analytics engine

To create an Athena workgroup:

  1. Open the Amazon Athena console.
  2. In the navigation pane, choose Workgroups.
  3. Choose Create workgroup.
  4. For Workgroup name, enter quick-demo.
  5. For Query result configuration, select Athena managed.
  6. Choose Create workgroup.

Your workgroup is ready immediately for querying data.

Load data and create business views

For Athena, you create tables using the TPC-H benchmark dataset that AWS provides in a public S3 bucket. This approach gives you 1.5 million customer records already optimized in Parquet format without requiring data loading.

To create tables and views in Athena:

  1. Open the Athena Query Editor from the console.
  2. Create a database for your analytics (create S3 bucket if it exists already):
    CREATE DATABASE IF NOT EXISTS athena_demo_db 
    COMMENT 'Analytics database for customer insights' 
    LOCATION 's3://my-analytics-data-lake-[account-id]/';

  3. Create an external table pointing to the TPC-H public dataset:
    CREATE EXTERNAL TABLE IF NOT EXISTS athena_demo_db.customer_csv ( 
      C_CUSTKEY INT, 
      C_NAME STRING, 
      C_ADDRESS STRING, 
      C_NATIONKEY INT, 
      C_PHONE STRING, 
      C_ACCTBAL DOUBLE, 
      C_MKTSEGMENT STRING, 
      C_COMMENT STRING 
    ) 
    
    ROW FORMAT DELIMITED 
    FIELDS TERMINATED BY '|' 
    STORED AS TEXTFILE 
    LOCATION 's3://redshift-downloads/TPC-H/2.18/100GB/customer/' 

  4. Create a business-friendly view for analytics:

Run the following SQL to create a view that aggregates customer account balances grouped by market segments.

CREATE VIEW athena_demo_db.customer_deep_analysis AS 
SELECT 
    c_custkey AS customer_id, 
    c_name AS customer_name, 
    c_mktsegment AS market_segment, 
    c_nationkey, 
    ROUND(c_acctbal, 2) AS account_balance, 
    CASE 
        WHEN c_acctbal < 0    THEN 'At-Risk' 
        WHEN c_acctbal < 2500 THEN 'Low' 
        WHEN c_acctbal < 5000 THEN 'Mid' 
        WHEN c_acctbal < 8000 THEN 'High' 
        ELSE 'Premium' 
    END                                                              
AS balance_tier, 

    ROUND(AVG(c_acctbal) OVER (PARTITION BY c_mktsegment), 2)        AS segment_avg, 
    ROUND(c_acctbal - AVG(c_acctbal) OVER (PARTITION BY c_mktsegment), 2) AS vs_segment_avg, 
    ROUND((c_acctbal - AVG(c_acctbal) OVER (PARTITION BY c_mktsegment)) 
          / NULLIF(STDDEV(c_acctbal) OVER (PARTITION BY c_mktsegment), 0), 2) AS segment_z_score, 
    RANK() OVER (PARTITION BY c_mktsegment ORDER BY c_acctbal DESC)  AS rank_in_segment, 
    NTILE(5) OVER (ORDER BY c_acctbal DESC)                          AS global_quintile 

FROM athena_demo_db.customer_csv 
ORDER BY c_acctbal DESC; 
  1. Verify your view from Athena with:
SELECT * FROM athena_demo_db.customer_deep_analysis limit 5;

Output from the SELECT query
Figure 6: Output from the SELECT query

Configure integration with Amazon Quick

To connect to Amazon Athena in Amazon Quick, follow these steps, consolidated from official AWS documentation and authorizing connections to Amazon Athena.

Authorize Quick to Access Athena, S3 Bucket for data, and S3 bucket for Athena Results.

Open the Amazon Quick Security Settings

  • Sign in to the Amazon Quick console as an administrator.
  • In the top-right corner, choose your profile icon, then select Manage account.
  • Under Permissions, choose AWS resources.AWS resource permissions
    Figure 7: AWS resource permissions

Enable Athena Access

  • Under Quick access to AWS services, choose Manage.
  • Locate Amazon Athena in the list of AWS services.
  • If Athena is already selected but access issues persist, clear the checkbox and re-select it to re-enable Athena.
  • Under Amazon S3, select S3 buckets.
  • Check the boxes next to each S3 bucket that Amazon Quick needs to access—including buckets used for Athena query results and any Redshift COPY source buckets.
  • Enable Write permission for Athena Workgroup to allow Amazon Quick to write Athena query results to S3 and choose Finish.
  • Choose Save to update the configuration.

The final step is to grant your Amazon Quick author permissions to query your database, Athena tables, and views. Configuration depends on whether AWS Lake Formation is enabled.

If AWS Lake Formation is not enabled

Permissions are managed at the Quick service role level through standard IAM-based S3 access control. Ensure that the Quick service role (for example, aws-quick-service-role-v0) has the appropriate IAM permissions for the relevant S3 buckets and Athena resources. No additional Lake Formation configuration is required.
If AWS Lake Formation is enabled

Lake Formation acts as the central authorization layer, overriding standard IAM-based S3 permissions. Grant permissions directly to the Amazon Quick author or IAM role.

To grant data permissions:

  1. Open the AWS Lake Formation console.
  2. Choose Permissions, then Data permissions, then Grant.
  3. Select the IAM user or role.
  4. Choose the required databases, tables, and columns.
  5. Grant SELECT at minimum; add DESCRIBE for dataset creation.
  6. Repeat for each user or role that requires access.

Create data source

Follow these steps to create an Athena data source on Amazon Quick.

  1. In the Amazon Quick console, navigate to Datasets and choose Data sources tab.
  2. Choose Create data source, then select the Amazon Athena card.
  3. Enter a Data source name (you can give any name of your choice), select your Athena workgroup (like quick-demo), and choose Validate connection.

Athena data source creation
Figure 8: Athena data source creation

  1. Choose Create data source.

Your Athena data source is now available for building datasets, dashboards, and Topics.

Use Amazon Quick generative AI features

The next steps, from 5–8, demonstrate Amazon Quick generative AI capabilities using Amazon Redshift as a data source. While we use Amazon Redshift in this example, you can substitute with Amazon Athena based on your specific requirements.

Create dashboards

Let’s start by creating datasets from the Amazon Redshift data source.

  1. In the left navigation pane, choose Datasets.
  2. On the Datasets page, choose Create Dataset.
  3. For the data source, select Amazon Redshift data source customer-rev-datasource.
  4. From the menu, choose mv_customer_revenue.

Select table to visualize
Figure 9: Select table to visualize

  1. You can choose one of the following query modes. For this post, select Directly query your data option and choose Visualize.
    • Import to SPICE for quicker analytics – Quick loads a snapshot into its in-memory engine for faster dashboard performance.
    • Directly query your data– Quick runs queries on demand against your query engine.
  2. Select Build icon to open a chat window. Enter “Show me orders by market segments” as the prompt. Note that you need Author Pro access to use this feature.

Build visualization using generative BI feature
Figure 10: Build visualization using generative BI feature

  1. You can change the visual type to a pie chart and add it to the analysis.

Change visual type
Figure 10: Change visual type

To publish your analysis as a dashboard

  1. After you add the visuals, choose Publish.
  2. Enter a name for the dashboard. For this post, use the Market Segment Dashboard.
  3. Choose Publish dashboard. Your dashboard is now available for viewing and sharing.

Create topics and spaces

To fully maximize enterprise data with AI, we must provide the right structure and context. That’s where Topics and Spaces come in. Topics act as natural language interfaces to your structured datasets, automatically analyzing your data, mapping fields, and adding synonyms. Business users can ask “What are total revenues by market segment?” and receive instant, visualized answers without writing a single line of SQL. Spaces bring together all of your related assets into a single collaborative workspace that democratizes data access, reduces context-switching, accelerates team onboarding, so everyone is working from the same trusted, AI-ready data sources.

To create a Quick topic

  1. From the Amazon Quick homepage, choose Topics, then choose Create topic.
  2. Enter a name for your topic. For this post, use Customer Revenue Analytics.
  3. Enter a description. For example:

The Customer Revenue Analytics topic is designed for business users (including analysts, sales operations teams, finance, and market segment owners who need to explore customer and revenue data without SQL expertise. It serves as a natural language interface over the mv_customer_revenue Amazon Redshift dataset, allowing users to ask plain-English questions like “What are total revenues by market segment?” and receive instant, visualized answers. By automatically mapping business language to the underlying schema, it democratizes access to revenue insights across the organization.

  1. Under Dataset, select mv_customer_revenue.
  2. Choose Create. The topic can take 15–30 minutes to enable depending on the data. During this time, Amazon Quick automatically analyzes your data, selects relevant fields, and adds synonyms.
  3. After the topic is enabled, take a few minutes to review and enrich it. The following are some example enrichments.
    1. Add column descriptions to clarify field meaning for business users.
    2. Define preferred aggregations (for example, sum compared to average for revenue fields).
    3. Confirm which fields are Dimensions and which are Measures.
  4. (Optional) To further refine how your topic interprets and responds to queries, add multiple datasets (for example, a customer CSV combined with a database view), custom instructions, filters, and calculated fields.

After your topic is created, its columns are available to add to a Space or to an Agent by selecting it as a data source.


Figure 11: Create a Quick Topic

Create a Space for your team

Spaces bring together dashboards, topics, datasets, documents, and other resources into organized, collaborative workspaces. By centralizing related assets in a single workspace, Spaces reduce context-switching, accelerate onboarding, so everyone is working from the same trusted data sources.

What to include in your Quick Space

  • Dashboard – Add the dashboard Market Segment Dashboard published from your mv_customer_revenue analysis. This gives team members instant access to visualizations such as revenue by market segment, top customers by order volume, and revenue distribution.
  • Topic – Connect the Customer Revenue Analytics (built on the mv_customer_revenue materialized view) to enable natural language queries directly against your Amazon Redshift data.
  • Optionally, you can upload supporting context to ground your team’s analysis:
    • Data dictionary or field definitions for mv_customer_revenue
    • Market segment definitions (AUTOMOBILE, BUILDING, FURNITURE, MACHINERY, HOUSEHOLD)
    • Business rules for revenue calculation (for example, how discounts are applied in the TPC-H model)
    • This implementation guide, so new team members can onboard quickly

To create the Quick Space

  1. From the left navigation menu, choose Spaces, then choose Create space.
  2. Enter a name, for example, Customer Revenue & Segmentation.
  3. Enter a description. For example:

Centralized workspace for customer revenue analysis powered by Amazon Redshift includes interactive dashboards, natural language query access to customer and segment data, and supports documentation for the TPC-H revenue model.

  1. Add knowledge by connecting the Market Segment Dashboard and topic Customer Revenue Analytics.
  2. You can invite team members, such as finance, sales operations, and segment owners, and set appropriate permissions.

Your Space is now ready for collaborative data exploration.


Figure 12: Create a Quick Space

Build chat agents

A custom chat agent delivers conversational AI experiences that understand business context and provide intelligent, grounded responses to user queries. These agents go beyond question-and-answer interactions. They synthesize knowledge from your dashboards, topics, datasets, and documents to explain trends, surface anomalies, guide users through complex analytics workflows, and recommend next steps.

Rather than requiring users to navigate multiple tools or write SQL queries, agents serve as a single conversational interface to your entire analytics environment. Agents can also connect to Actions, pre-built integrations with enterprise tools such as Slack, Microsoft Teams, Outlook, and SharePoint, enabling them to answer questions and trigger real-world workflows, send notifications, create tasks, and interact with external systems directly from the conversation. Custom agents can be tailored to specific business domains, teams, or use cases so that responses align with organizational terminology, data definitions, and business processes. After created, agents can be shared across teams, enabling consistent, actionable, AI-powered data access at scale. For teams working with the mv_customer_revenue dataset, we recommend creating a dedicated Customer Revenue Analysis Agent. This is a purpose-built conversational assistant grounded in your Amazon Redshift data, dashboards, and the Customer Revenue & Segmentation Space.

Create a Quick chat agent

There are two ways that you can use Amazon Quick to create a Quick agent. You can use the navigation menu or directly from Space. The following steps walk you through creating one from the navigation menu.

To create a Quick chat agent

  1. From the left navigation menu, choose Agents, then choose Create agent.
  2. Enter a name for your agent, for example, Customer Revenue Analyst.
  3. Enter a description. For example:

An AI assistant for analyzing customer revenue, market segment performance, and order trends using our Amazon Redshift or data warehouse.

  1. Under Knowledge Sources, add the Customer Revenue & Segmentation Space as a data source. This gives your agent access to the dashboards, topics, and reference documents you’ve already built.
  2. (Optional) Define custom persona instructions to align the agent’s responses with your business context. For example, specifying preferred terminology, response style, or the types of questions it should prioritize.
  3. Choose Launch chat agent.
  4. Start having a conversation with your data. You are welcome to ask any questions. The following are some examples.
    • Which market segment generated most revenue?
    • Show me order trends


Figure 13: Create a Quick Chat agent

To share your Quick chat agent

After your agent is published, choose Share and invite team members or share it across your organization. Custom agents can be tailored to specific business contexts so that different teams can get AI assistance that speaks their language, without needing to configure anything themselves.

Create Quick Flows

Quick Flows automate repetitive tasks and orchestrate multi-step workflows across your entire analytics environment. This removes manual effort, reducing human error, and ensuring consistent execution of critical business processes. Flows can be triggered on a schedule or launched on demand, giving you flexible control over when and how automation runs.

You can build flows that span the full analytics lifecycle: monitoring data quality and flagging anomalies, generating and distributing scheduled reports to stakeholders, and triggering downstream actions in integrated systems such as Slack, Outlook. Amazon Quick gives you three ways to create a flow, so whether you prefer a no-code conversation or a visual step-by-step builder, there’s an option that fits how you work.

To create a flow from chat

  1. While conversing with My Assistant or a custom agent, describe the workflow that you want to automate in plain English.
  2. Amazon Quick generates the flow and offers to create it directly from your conversation — no configuration screens required.

To create a flow from a natural language description

  1. From the left navigation menu, choose Flows, then choose Create flow.
  2. Enter a plain-English description of your workflow. For example:

” Query revenue data by market segments. Filter by order count and all dates. Search web for comparable relevant market trends. Generate formatted summary reports providing market summary and look ahead per segment. ”

  1. Amazon Quick automatically generates the complete workflow with all the necessary steps.
  2. Optionally, you can add additional steps.
  3. Choose Run Mode to test the Flow.
  4. After your flow is created, share it with team members or publish it to your organization’s flow library, so everyone benefits from the same automation without having to rebuild it independently.


Figure 14: Create a Quick Flow to generate summaries and publish dashboards

For more complex flow, review weekly customer revenue summary flow as an example.

  1. Queries the mv_customer_revenue materialized view in Amazon Redshift for the latest weekly revenue figures by market segment.
  2. Compares results against the prior week to calculate segment-level variance.
  3. Generates a formatted summary report and publishes it to the Customer Revenue & Segmentation Space.
  4. Sends a notification through email or Slack to finance, sales operations, and segment owners with a direct link to the updated dashboard.
  5. Flags any segment where revenue has declined more than a defined threshold, routing an alert to the appropriate owner for follow-up.

This flow transforms what might otherwise be a manual, multi-step reporting process into a fully automated pipeline, so stakeholders receive consistent, timely revenue insights without analyst intervention and saving analysts an estimated 3–5 hours per week. For detailed guidance on creating and managing flows, see Using Amazon Quick Flows. Also review Create workflows for routine tasks demo.

Cleanup

Consider deleting the following resources created while following this post to avoid incurring costs. We encourage you to use the trials at no cost as much as possible to familiarize yourself with the features described.

  1. Delete the Amazon Redshift Serverless workgroup and namespace.
  2. Delete Athena workgroup and S3 Buckets.
  3. Delete the Amazon Quick account used while following this post. If you used an existing account, delete the data sets, dashboards, topics, spaces, agents and flows created.

Conclusion

This integrated approach to business intelligence combines the power of AWS SQL analytics engines with Amazon Quick generative AI capabilities to deliver comprehensive analytics solutions. By following these implementation steps, you establish a foundation for traditional BI reporting, interactive dashboards, natural language data exploration, and intelligent workflow automation. The architecture scales from proof-of-concept implementations to production deployments, transforming how organizations access and act on data insights. For more information about Amazon Quick features and capabilities, see the Amazon Quick documentation. To learn more about Amazon Redshift, visit the Amazon Redshift product page. For Amazon Athena details, see the Amazon Athena product page.


About the authors

“Satesh Sonti”

Satesh is a Principal Analytics Specialist Solutions Architect based in Atlanta, specializing in building enterprise data platforms, data warehousing, and analytics solutions. He has over 20 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

“Ramon Lopez”

Ramon Lopez is a Principal Solutions Architect for Amazon Quick. With many years of experience building BI solutions and a background in accounting, he loves working with customers, creating solutions, and making world-class services. When not working, he prefers to be outdoors in the ocean or up on a mountain.

How AWS KMS and AWS Encryption SDK overcome symmetric encryption bounds

Post Syndicated from Panos Kampanakis original https://aws.amazon.com/blogs/security/how-aws-kms-and-aws-encryption-sdk-overcome-symmetric-encryption-bounds/

If you run high-scale applications that encrypt large volumes of data, you might be concerned about tracking encryption limits and rotating keys. This post explains how AWS Key Management Service (AWS KMS) and the AWS Encryption SDK handle Advanced Encryption Standard in Galois Counter Mode’s (AES-GCM) encryption limits or bounds automatically by using derived key methods so you don’t have to. These methods generate a new derived key Kd from the main key K by using a random nonce. That way, encryption is done with a unique key each time, and K can be used for much longer. Similar derived key modes have been proposed in various schemes recently like (KC-)XAES, DNDK v2, and ia.cr/2020/1153.

Symmetric encryption bounds

Symmetric encryption algorithms encrypt large amounts of data in transit and at rest. Modern ciphers also authenticate data using an authentication tag — these are called Authenticated Encryption with Additional Data (AEAD) ciphers. Examples of AEAD ciphers include AES-GCM and ChaCha20/Poly1305.

AES-GCM is the most widely used encryption algorithm and was standardized by NIST in SP 800-38D. AES-GCM uses a 128- or 256-bit key K and a (usually 96-bit) initialization vector (IV) to encrypt and authenticate a plaintext P. It also authenticates additional authenticated data (AAD). The output is a ciphertext C and an authentication tag T:
(C, T) = AES-GCM(K, IV, AAD, P)

At decryption, the recipient decrypts C and verifies the tag T by using K, IV and AAD and produces the original plaintext P (assuming the tag was authenticated successfully).

Encryption invocation limits

When encrypting data, it’s critical that the K, IV tuple does not repeat for the life of the key K. Otherwise, the security properties of AES-GCM are lost. SP 800-38D requires an implementation to have a probability of key and IV reuse less than one in 4.29 billion (<2-32). This can be achieved by using a deterministic IV that doesn’t repeat or a random IV. If a random IV is used, then it is necessary to rekey after 2-32 encryptions. For example, common protocols like TLS or IKEv2/IPsec prevent (K, IV) collisions by using deterministic (that is, starting from a random value and incrementing) IVs per connection.

Data bounds

Assuming the probability of an (K, IV) collision is statistically insignificant (<2-32), there are still data bounds when encrypting large amounts of plaintexts with the same key K. The block counter in AES-GCM is 32-bits, which leads to a limit of 232-2 bytes (68.72 GB) per encryption operation (per (K, IV) pair). Additionally, a failure to restrict the total amount of data reduces the security guarantees an adversary can distinguish between two different plaintexts, that is knowing which of two messages are encrypted in the ciphertext. The higher protection of indistinguishability, the lower the total number of bytes you can encrypt. NIST’s specification, SP 800-38D, suggests a limit of 268 bytes protected under a single key K which provides an indistinguishability probability of 50%. More conservative security margins are sometimes used, based on different analyses (ia.cr/2024/051, 10.1145/3243734.3243816). AWS sets a more conservative margin too, enforcing a negligible indistinguishability probability (<2-32) by default.

Once you reach the AES-GCM data bounds for a given security margin, you need to rotate the symmetric key. Such limits (for example, 232 encryptions per key with random IVs, or encrypting the maximum total data per key) could be reached in modern, high-scale encryption use cases. Tracking these limits across distributed systems with many concurrent sessions adds operational complexity. We have shared these challenges with using AES-GCM at the scale of AWS in a writeup and a presentation in NIST’s third NIST Workshop on Block Cipher Modes of Operation in 2023.

How AWS KMS uses derived keys

AWS KMS is a managed service that you can use to create and control the keys used to encrypt and sign data. The AWS KMS Encrypt API supports symmetric and asymmetric encryption. For symmetric key encryption, AWS KMS uses AES-GCM with 256-bit keys to encrypt a plaintext up to 4 KB in size. The AWS KMS request includes the plaintext, and the symmetric key identifier (KeyId) of the symmetric customer managed key (CMK) stored in KMS.

A symmetric key Encrypt API call to AWS KMS uses the CMK to derive a symmetric encryption key before encrypting the plaintext. AWS KMS generates a random 128-bit nonce N and produces a 256-bit symmetric key from the main key K specified in the KeyId by using a key derivation function (KDF). A KDF takes in a key, a label and context, an invocation-specific nonce N, and an output length LKm in bytes, and produces key material of that length as Kmat = KDF(K, <label>, <context>, N, LKm). <label> is usually an application- or invocation-specific value. <context> includes invocation-specific input. For AWS KMS, the KDF function is a NIST SP 800-108r1 Counter Mode KDF producing 256 bits of keying material with HMAC-SHA256 as the pseudorandom function. Kd is essentially produced with one call to HMAC-SHA256 with key K as:
Kd = HMAC-SHA256(K, <ctx>),
where <ctx> consists of a counter value concatenated with constants and N.

Subsequently, AWS KMS generates a 96-bit random IV and encrypts the input plaintext input P with AES-GCM as (C, T) = AES-GCM(Kd, IV, AAD, P).

AWS KMS returns a CiphertextBlob that includes the IV, nonce N, ciphertext and tag (C,T) so that the CiphertextBlob can be decrypted on subsequent calls to the Decrypt API.

Intuitively, the 128-bit random nonce used to derive a per encryption key under a CMK ensures that a caller can go way over the 232 limit on the number of encryptions they can make under the CMK. Furthermore, the limit of 4 KB on the payload size for an AWS Encrypt call ensures the total amount of data encrypted under an encryption key stays well below NIST or other more conservative total encryption bounds. For more details and the mathematics of the security underpinnings of this scheme, see Key Management Systems at the Cloud Scale.

How AWS Encryption SDK applies derived key modes per invocation

The AWS Encryption SDK is a client-side encryption library used for encrypting and decrypting data. It can be configured to use data key caching to reduce API calls when encrypting multiple payloads. Using a nonce-based derived key for each AES-GCM encryption invocation eliminates the need for customers to keep track of the total amount of data they encrypt under a single data key.

Although the AWS Encryption SDK provides a lot of flexibility to accommodate many encryption scenarios, the default configuration handles key derivation and frame sizing automatically, so you don’t need to tune these settings for most use cases. To derive a different key per invocation, like AWS KMS, it uses a randomly generated value, N, the main key K, and some invocation-specific context in the KDF. N is 256 bits in the default configuration. The underlying KDF is the HMAC-based Extract-and-Expand Key Derivation Function (HKDF) with SHA512 as the default hash. Kd is essentially produced with one HKDF call with key K as:
Kd = HKDF(K, salt=<lbl>, info=<ctx>, 32),
where <lbl> is a constant and <ctx> consists of constants concatenated with a random 256-bit value in the default configuration.

Subsequently, the AWS Encryption SDK uses the derived key Kd to encrypt user content, broken into 4-KB frames by default. Each frame plaintext Pf is encrypted with AES-GCM with a deterministic IV as (C, T) = AES-GCM(Kd, IV, AAD, Pf).

The 96-bit deterministic IV consists of the frame counter frameID, where frameID<232. The additional authenticated data AAD is specific to the Encryption SDK data frame. At decryption, the recipient derives Kd from K in the same way and decrypts the ciphertext C to produce the frame plaintext Pf and validates the authentication tag T.

The 4 KB frame size ensures that by default no more than 244 bytes (232 frames of 4 K bytes each) of data can be encrypted under a single encryption key. This is well below the NIST suggested bound (268), even with data key caching. It is also well below our conservative requirement of <2-32 indistinguishability probability. The limit of invocations per key, even with data key caching, exceeds the encryption counts in most high-scale applications.

Note: While the AWS Encryption SDK makes conservative choices in its default configuration, if you’re using legacy version 1.0 or making configuration changes, you might have lower security guarantees. For example, a custom maximized frame size of 232-1 bytes would lead to larger total plaintext size which is still below the 268 NIST suggested limit, but not below other conservative bounds.

Note that the default AWS Encryption SDK configuration also provides lesser-known security properties, like key commitment. The commitment string is produced similarly to the derived key, by using K and HKDF.

Conclusion

By deriving a unique key per encryption call, AWS KMS and the AWS Encryption SDK eliminate the need to manually track AES-GCM limits.

For the academic basis for AES-GCM’s bounds, see SP 800-38D and draft-irtf-cfrg-aead-limits. To read more on the cryptographic analysis of the key derivation scheme used in KMS, see Key Management Systems at the Cloud Scale. For more details on the Encryption SDK AES-GCM key derivation, see the AWS Encryption SDK algorithms reference.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support.
 

Panos Kampanakis
Panos Kampanakis

Panos is a Principal Security Engineer at AWS. He has experience with cybersecurity, applied cryptography, security automation, and vulnerability management. He has coauthored publications on cybersecurity and participated in various security standards bodies to provide common interoperable protocols and languages for security information sharing, cryptography, and public-key infrastructure. Currently, he works with engineers and industry partners to provide cryptographically secure tools, protocols, and standards.
Matt Campagna
Matt Campagna

Matthew is a Cryptographer and Sr. Principal Engineer at Amazon Web Services. He manages the design and review of cryptographic solutions across the company and leads the migration to post-quantum cryptography. In his spare time, he searches Seattle for the perfect Korean Fried Chicken.
Patrick Palmer
Patrick Palmer

Patrick is a Principal Security Specialist Solutions Architect at AWS. He helps customers around the world use AWS services in a secure manner and specializes in cryptography. When not working, he enjoys spending time with his growing family and playing video games.

Streamline Apache Kafka topic management with Amazon MSK

Post Syndicated from Swapna Bandla original https://aws.amazon.com/blogs/big-data/streamline-apache-kafka-topic-management-with-amazon-msk/

If you manage Apache Kafka today, you know the effort required to manage topics. Whether you use infrastructure as code (IaC) solutions or perform operations with admin clients, setting up topic management takes valuable time that could be spent on building streaming applications.

Amazon Managed Streaming for Apache Kafka (Amazon MSK) now streamlines topic management by supporting new topic APIs and console integration. You can programmatically create, update, and delete Apache Kafka topics using familiar interfaces including AWS Command Line Interface (AWS CLI), AWS SDKs, and AWS CloudFormation. With these APIs, you can define topic properties such as replication factor and partition count and configuration settings like retention and cleanup policies. The Amazon MSK console integrates these APIs, bringing all topic operations to one place. You can now create or update topics with a few selections using guided defaults while gaining comprehensive visibility into topic configurations, partition-level information, and metrics. You can browse for topics within a cluster, review replication settings and partition counts, and go into individual topics to examine detailed configuration, partition-level information, and metrics. A unified dashboard consolidates partition topics and metrics in one view.

In this post, we show you how to use the new topic management capabilities of Amazon MSK to streamline your Apache Kafka operations. We demonstrate how to manage topics through the console, control access with AWS Identity and Access Management (IAM), and bring topic provisioning into your continuous integration and continuous delivery (CI/CD) pipelines.

Prerequisites

To get started with topic management, you need:

  • An active AWS account with appropriate IAM permissions for Amazon MSK.
  • An existing Amazon MSK Express or Standard cluster using Apache Kafka version 3.6 and above.
  • Basic familiarity with Apache Kafka concepts like topics, partitions, and replication.
  • AWS CLI installed and configured (for command line examples).

Creating topics

The MSK console provides a guided experience with sensible defaults while still offering advanced configuration options when you need them.

  1. Navigate to the Amazon MSK console and select your cluster.
  2. Choose the Topics tab, then choose Create topic.
  3. Enter a topic name (for example, customer-orders).
  4. Specify the number of partitions (use the guided defaults or customize based on your needs).
  5. Set the replication factor. Note that Express brokers improve the availability and durability of your Amazon MSK clusters by setting values for critical configurations and protecting them from common misconfiguration. If you try to create a topic with a replication factor value other than 3, Amazon MSK Express will create the topic with a replication factor of 3 by default.
  6. (Optional) Configure advanced settings like retention period or message size limits.
  7. Choose Create topic.

The console validates your configuration and creates the topic. You can create multiple topics simultaneously with the same configuration settings. These topic API responses reflect data that updates approximately every minute. For the most current topic state after making changes, wait approximately one minute before querying.

Configuration considerations

When choosing configuration options, consider your workload requirements:

Viewing and monitoring topics

After you create topics, the MSK console provides comprehensive visibility into their configuration. When you select a specific topic, you will see detailed information:

  • Partitions tab: Shows the distribution of partitions across brokers, including leader assignments and in-sync replica status showcasing Broker IDs for leader and replicas.
  • Configuration tab: Displays all topic-level configuration settings.
  • Monitoring tab: Integrates with Amazon CloudWatch to show metrics like bytes in/out, message rates, and consumer lag.

Updating topic configurations

As your workload requirements evolve, you might need to adjust topic configurations. You can modify various topic settings depending on your cluster type. For example:

  • Retention settings: Adjust retention.ms (time-based) or retention.bytes (size-based) to control how long messages are retained.
  • Message size limits: Modify max.message.bytes to accommodate larger or smaller messages.
  • Compression: Change compression.type to optimize storage and network usage.

Configuration changes take effect immediately for new messages. Existing messages remain subject to the previous configuration until they age out or are consumed.

Deleting topics

Amazon MSK also provides APIs for deleting topics that are no longer in use. Before deleting a topic, verify that:

  • No active producers are writing to the topic
  • All consumers have finished processing messages
  • You have backups if you need to retain the data
  • Downstream applications won’t be impacted

Important: Topic deletion permanently removes all messages in the topic.

Control access with IAM

Beyond streamlining topic operations, you also need appropriate access controls. Access control uses IAM, so you define permissions using the same model that you apply to other AWS resources. Amazon MSK uses a two-level permission model:

  • Resource-level permissions: An IAM policy that enforces which operations the cluster will allow
  • Principal-level permissions: IAM policies attached to Roles or Users that enforce which operations a principal is allowed to perform on a cluster

With this separation, you can control access depending on your organizational needs and access patterns for your cluster. Refer to the IAM permissions documentation for IAM permissions required for topic management for the Amazon MSK cluster.

You can grant your operations team broad access to manage all topics and restrict application teams to manage only their own topics. The permission granularity that you need is available through standard IAM policies. If you’ve already configured IAM permissions for Apache Kafka topics, they work immediately with the new functionality without any migration or reconfiguration.

Here is a sample IAM policy definition that allows Describe Topic API

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "kafka-cluster:Connect"
            ],
            "Resource": [
                "arn:aws:kafka:us-east-1:111111111111:cluster/iam-auth-acl-test/a6b5c6d5-f74f-4dbc-ad14-63fb5e87fe4f-2"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "kafka-cluster:DescribeTopic",
                "kafka-cluster:DescribeTopicDynamicConfiguration"
            ],
            "Resource": [
                "arn:aws:kafka:us-east-1:111111111111:topic/iam-auth-acl-test/a6b5c6d5-f74f-4dbc-ad14-63fb5e87fe4f-2/*"
            ]
        }
    ]
}

This IAM policy grants the necessary permissions to describe Kafka topics in your Amazon MSK cluster. The policy includes three key permissions:

  • kafka-cluster:Connect – Allows connection to the specified MSK cluster
  • kafka-cluster:DescribeTopic – Enables viewing topic details
  • kafka-cluster:DescribeTopicDynamicConfiguration – Enables viewing topic dynamic configuration

The policy is scoped to a specific cluster ARN and applies to all topics within that cluster using the wildcard pattern /*. Replace the placeholder Amazon MSK cluster ARN with your MSK cluster ARN.

Infrastructure as Code

If you manage infrastructure as code (IaC), you can now define topics alongside clusters in your CloudFormation templates:

Resources:
    OrdersTopic:
      Type: AWS::MSK::Topic
      Properties:
        ClusterArn: !GetAtt MyMSKCluster.Arn
        TopicName: orders
        NumPartitions: 6
        ReplicationFactor: 3
        Config:
          retention.ms: "604800000"

This approach brings topic provisioning into your CI/CD pipelines.

Availability and pricing

The new Amazon MSK topic management experience is available today for Standard and Express Amazon MSK clusters using Apache Kafka version 3.6 and above in all AWS Regions where Amazon MSK is offered, at no additional cost.

Cleanup

To avoid incurring additional charges to your AWS account, ensure you delete all resources created during this tutorial, including:

  • Amazon MSK cluster
  • Any Kafka topics created
  • Associated AWS resources (security groups, VPCs, etc., if created specifically for this blog)

Remember to verify that all resources have been successfully removed to prevent ongoing costs.

Conclusion

Topic management has been a persistent pain point for Apache Kafka operations. The new integrated experience in Amazon MSK now reduces operational friction by bringing topic operations into the AWS tools that you use every day. You now have a consistent, streamlined way to handle these operations for all Apache Kafka topics across multiple MSK clusters. This capability reflects our commitment to reducing operational complexity in Apache Kafka. You get the reliability and performance of Apache Kafka without the operational overhead that traditionally comes with it. Your team spends less time on infrastructure maintenance and more time building streaming applications that drive your business forward.

Ready to start streamlining your topic management? Start managing your topics today through the Amazon MSK console or by visiting the Amazon MSK documentation.


About the authors

Swapna Bandla

Swapna is a Senior Streaming Solutions Architect at AWS. With a deep understanding of real-time data processing and analytics, she partners with customers to architect scalable, cloud-native solutions that align with AWS Well-Architected best practices. Swapna is passionate about helping organizations unlock the full potential of their data to drive business value. Beyond her professional pursuits, she cherishes quality time with her family.

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. They work with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Judy Huang

Judy is a Senior Product Manager for Amazon Managed Streaming for Apache Kafka (MSK) at AWS. She is passionate about real-time data systems and helping organizations unlock the value of streaming data at scale. Her work focuses on improving how customers manage Kafka infrastructure and building capabilities that make streaming platforms more accessible, resilient, and integrated with the broader data ecosystem.

How to set up an air-gapped VPC for Amazon SageMaker Unified Studio

Post Syndicated from Rohit Vashishtha original https://aws.amazon.com/blogs/big-data/how-to-set-up-an-air-gapped-vpc-for-amazon-sagemaker-unified-studio/

Organizations are finding significant value using an integrated experience for all your data and AI with Amazon SageMaker Unified Studio. However, many organizations require strict network control to meet security and regulatory compliance requirements like HIPAA or FedRAMP for their data and AI initiatives, while maintaining operational efficiency.

In this post, we explore scenarios where customers need more control over their network infrastructure when building their unified data and analytics strategic layer. We’ll show how you can bring your own Amazon Virtual Private Cloud (Amazon VPC) and set up Amazon SageMaker Unified Studio for strict network control.

Solution overview

The solution covers complete technical know-how of a fully private network architecture using Amazon VPC with no public internet exposure. The approach leverages AWS PrivateLink through VPC endpoints to provide a secure communication between SageMaker Unified Studio and essential AWS services entirely over the AWS backbone network.

The architecture consists of three core components: a custom VPC named airgapped with multiple private subnets distributed across at least three Availability Zones for high availability, a comprehensive set of VPC interface and gateway endpoints for service connectivity, and the SageMaker Unified Studio domain configured to operate exclusively within this isolated environment. This design helps ensure that sensitive data never traverses the public internet while maintaining full functionality for data cataloging, query execution, and machine learning workflows.

By implementing this air-gapped configuration, organizations gain granular control over network traffic, simplified compliance auditing, and the ability to integrate SageMaker Unified Studio with existing private data sources through controlled network pathways. The solution supports both immediate operational needs and long-term scalability through careful IP address planning and modular endpoint architecture.

Prerequisites

The set up requires you to have an existing VPC (for this post, we’ll refer to the name as airgapped but in reality, it refers to the VPC you would like to securely set up SageMaker Unified Studio). If you don’t have an existing VPC, you can follow SageMaker Unified Studio domain quick create administrator guide to get started.

The high level steps to create a VPC meeting minimum requirements for SageMaker Unified Studio are as follows:

  1. In the AWS Management Console, navigate to the VPC console.
  2. Choose Create VPC.
  3. Select the VPC and more radio button.
  4. For Name tag auto-generation, enter airgapped or a name of your choice.
  5. Keep the default values for IPv4 CIDR block, IPv6 CIDR block, Tenancy, NAT gateways, VPC endpoints, and DNS options.
  6. Select 3 for Number of Availability Zones (AZs).
  7. Select 0 for Number of public subnets.
  8. Choose Create VPC.

This produces the following VPC resource map:

Figure 1 - VPC configuration

Figure 1 – VPC configuration

Set up SageMaker Unified Studio

Now, we will set up SageMaker Unified Studio in an existing VPC, named airgapped-vpc.

  1. Navigate to the SageMaker console, choose Domains in the navigation pane.
  2. Choose Create Domain.
  3. For How do you want to set up your domain?, select Quick set up.
  4. Expand the Quick set up settings
  5. Provide a name for your domain, such as airgapped-domain.
  6. For Virtual private cloud (VPC), select airgapped-vpc.
  7. For subnets, select a minimum of two private subnets.
  8. Choose Continue.
  9. Enter an email address to create a user in AWS IAM Identity Center.
  10. Choose Create domain.
  11. Once the domain is created, choose Open unified studio or use SageMaker Unified Studio URL under Domain details to access SageMaker Unified Studio.

    Figure 2 - Amazon SageMaker Unified Studio URL Welcome Page

    Figure 2 – Amazon SageMaker Unified Studio URL Welcome Page

  12. After logging in to SageMaker Unified Studio, create a project using the guided wizard.
  13. Once the project is created, we need to add the necessary VPC endpoints to allow traffic from the project to communicate to AWS services.
  14. S3 Gateway VPC endpoint was already selected as part of VPC creation step 5 in prerequisites and thus created by default. Now we must add two more VPC endpoints for Amazon DataZone and AWS Security Token Service as illustrated in following step.

These are the minimum set of VPC endpoints to allow using the tooling within SageMaker Unified Studio. For a list of other mandatory and non-mandatory VPC endpoints refer to the tables in the latter part of this post.

Create an interface endpoint

To create an interface endpoint, complete following steps:

  1. Go to the SageMaker Unified Studio Project details page and copy the Project ID.
    Figure 3 - SageMaker Unifed Studio Project Details PageFigure 3 – SageMaker Unifed Studio Project Details Page
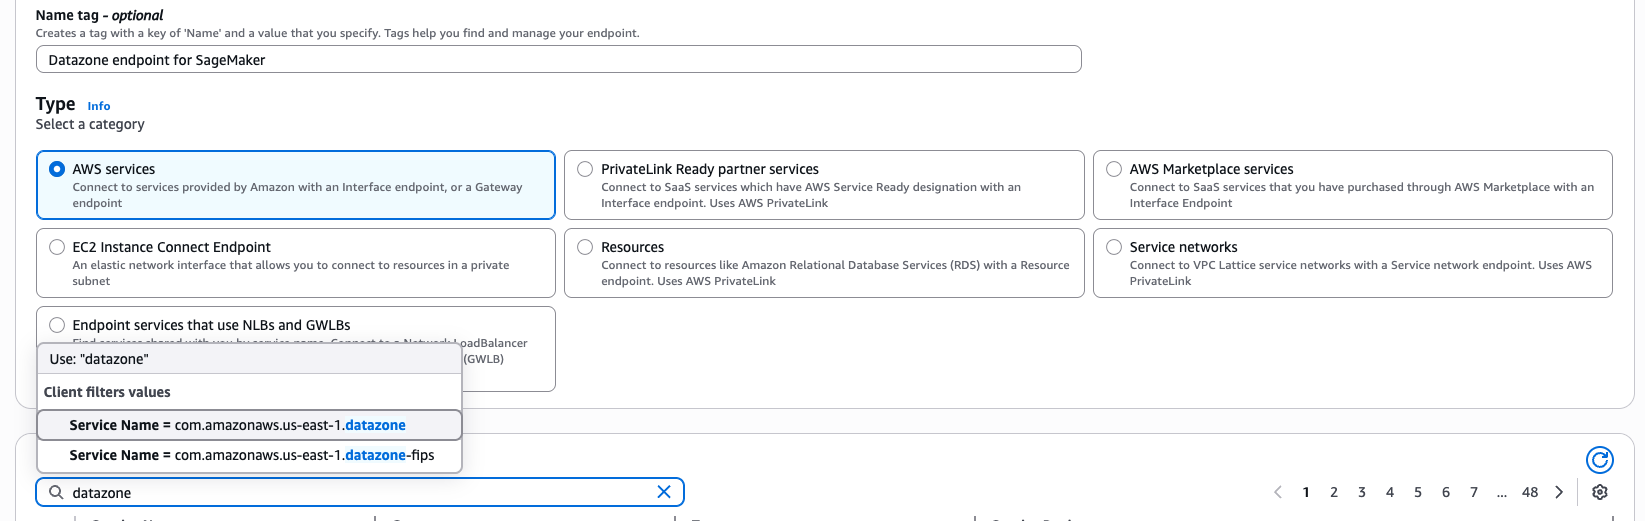
  2. Go to the VPC console and choose Endpoints.
  3. Choose Create Endpoint.
  4. Enter a name for the endpoint, for example, DataZone endpoint for SageMaker Unified Studio.
  5. For AWS Services, enter DataZone.
    Figure 4 - Interface Endpoint creation wizard for AWS Service datazone

    Figure 4 – Interface Endpoint creation wizard for AWS Service datazone

  6. Select Service Name = com.amazonaws.us-east-1.datazone from the available options.
    Figure 5 - Interface Endpoint creation wizard network settings

    Figure 5 – Interface Endpoint creation wizard network settings

  7. Select the subnets in the airgapped-vpc that you created earlier.
  8. Filter the Security Groups by pasting the copied Project ID.
  9. Select the security group with Group Name datazone-<project-id>-dev.
  10. Choose Create Endpoint.
  11. Repeat the same steps to create a VPC endpoint for AWS STS.
  12. Once the VPC endpoints are created, validate connectivity in the SageMaker project by running a SQL query or using a Jupyterlab notebook.

For a successful domain and project which does not get into any service level usage, the mandatory VPC endpoints to be created are: S3 Gateway, DataZone, and STS interface endpoints. For other service usage dependent operations like authentication, data preview and working with compute, you would require other mandatory service specific endpoints explained later in this post.

Best practices for VPC set up for various use cases

When setting up SageMaker Unified Studio domain and project profiles, you need to specify the VPC network, subnets, and security groups. Here are some best practices around IP allocation, usage volume and expected growth to consider for different use cases within enterprises.

Production and enterprise use cases

If your organization require strict network control to meet security and compliance requirements for data and AI initiatives, consider following best practices in your production environment.

  • Use the bring-your-own (BYO) VPC approach to comply with company-specific networking and security requirements.
  • Implement private networking using VPC endpoints to keep traffic within the AWS backbone.
  • Use at least two private subnets across different Availability Zones.
  • Enable DNS hostnames and DNS Support.
  • Disable auto-assign public IP on subnets.
  • Plan IP capacity for at least 5 years. A prescriptive guidance for SageMaker Unified Studio is shared in VPC and Networking details section later in this post. Consider the following:
    • Number of users
    • Number of apps per user
    • Number of unique instance types per user
    • Average number of training instances
    • Expected growth percentage

Testing and non-production use cases

For development, testing, non-prod environment where use cases don’t have stringent security and compliance requirements, use automated setup for quick experiments. Use sample CloudFormation github templates as part of the SageMaker Unified Studio express set up, to automate domain and project creation. However, this includes an Internet Gateway which may not be suitable for security-sensitive environments.

Private networking use cases

VPCs with private subnets require essential service endpoints to allow client resources like Amazon EC2 instances to securely access AWS services. The traffic between your VPC and AWS services remains within AWS network avoiding public internet exposure.

  • Implement all mandatory VPC endpoints for core services (SageMaker, DataZone, Glue, and more).
  • Add optional endpoints based on specific service needs, like IPv4 endpoints, dual-stack endpoints, and FIPS endpoints to programmatically connect to an AWS service.
  • Work with network administrators for:
    • Preinstalling needed resources through secure channels like private subnets and self-referencing inbound rules in security groups to enable limited access.
    • Allowlisting only necessary external connections like NAT gateway IP and bastion host access in firewall rules.
    • Setting up appropriate proxy configurations if required.

External data source access use cases

Consider the following when working with external systems like third-party SaaS platforms, on-premises databases, partner APIs, legacy systems, or external vendors.

  • Consult with network administrators for appropriate connection methods.
  • Consider AWS PrivateLink integration where available.
  • Implement appropriate security measures for non-AWS data your source documents.
  • For High Availability:
    • Deploy across at least three different Availability Zones (at least two for AWS Regions with only two AZs).
    • Verify there’s a minimum of three free IPs per subnet.
    • Consider larger CIDR blocks (/16 recommended) for future scalability.

VPC and networking details

In this section, we provide details of each networking aspect starting with choice of VPCs, network connectivity details for integrated services to work, the basis of VPC and subnet requirements, and finally the VPC endpoints required for private service access.

VPC

At a high level, you have two options to supply VPCs and subnets:

  1. Bring-your-own (BYO) VPC. This is typically the case for most customers, as most have company specific networking and security requirements to reuse an existing VPC, or to create a VPC that are compliant with those requirements.
  2. Create VPC with the SageMaker quick set up template. When creating a SageMaker Unified Studio domain (DataZone V2 domain in CloudFormation) through the automated quick set up, you will be shown a Quick create stack wizard in CloudFormation which creates VPCs and subnets used to configure your domain.

    Note: The quick create stack using template URL is not intended for production use. The template creates an Internet Gateway, which is not allowed in many enterprise settings. This is only appropriate if you are either trying out SageMaker Unified Studio or, running SageMaker Unified Studio for use cases that don’t have stringent security requirements.If you choose this option, you start with SageMaker console, navigate to domains and click Create domain button, followed by Create VPC button. You will navigate to CloudFormation and click on Create stack button to create a sample VPC named SageMakerUnifiedStudio-VPC with just one-click for trying out SageMaker Unified Studio.

Figure 6 - Create VPC button in SageMaker Unified Studio Create Domain Wizard

Figure 6 – Create VPC button in SageMaker Unified Studio Create Domain Wizard

Cost estimation for recommended VPC set up

The exact cost depends on the configuration of your VPC. For more complex networking set ups (multi-VPC), you may need to use additional networking components such as a Transit Gateway, Network Firewall, and VPC Lattice. These components may incur charges, and cost depends on usage and AWS Region. Interface VPC endpoints are charged per availability zone. They also have a fixed and a variable component in the pricing structure. Use the AWS Pricing Calculator for a detailed estimate.

Network Connectivity

With regards to connectivity to the underlying AWS services integrated within SageMaker Unified Studio, there are two ways to enable connectivity (these are not Studio specific, these are standard ways to enable network connectivity within a VPC). This is an important security consideration that depends on your organization’s security policies.

  1. Through the public Internet. Your traffic will traverse over the public Internet through an Internet Gateway in your VPC.
    1. Your VPC must have an Internet Gateway attached to it.
    2. Your public subnet must have a NAT Gateway. In addition, your public subnet’s route table must have a default route (0.0.0.0 for IPv4) to the Internet Gateway. This route is what makes the subnet public.
    3. Your private subnets must have a default route to the public subnet’s NAT Gateway.
  2. Through the AWS backbone. Your traffic will remain within the private AWS backbone through PrivateLink (by provisioning Interface and Gateway endpoints for the necessary AWS services in each Availability Zone).
    1. A list of all the AWS services integrated into Studio and the VPC endpoints required can be found in section VPC Endpoints covered later in this post.
    2. For non-AWS resources, certain external providers of these services may offer PrivateLink integration. Check with each provider’s documentation and your network administrator to understand the most suitable way to connect to these external providers.

In a private networking scenario, you will need to consider whether you need connectivity to non-AWS resources in a way that’s compliant with your organization’s security policies. A few examples include the following:

  1. If you need to download software in your remote IDE host (for example, command line programs, such as Ping and Traceroute)
  2. If you have code that connects to external APIs.
  3. If you use software (such as JupyterLab or Code Editor extensions) that rely on external APIs.
  4. If you depend on software dependencies hosted in the public domain (such as Maven, PyPi, npm)
  5. If you need cross-Region access to certain resources (such as access to S3 buckets in a different Region)
  6. If you need functionality whose underlying AWS services do not have VPC endpoints in all Regions or any Region.
    1. Amazon Q (powers Q and code suggestions)
    2. SQL Workbench (powers Query Editor)
    3. IAM (powers Glue connections)

If you need to connect to data sources outside of AWS (such as Snowflake, Microsoft SQL Server, Google BigQuery)
Enterprise network administrators must also complete either of the following prerequisites to handle private networking scenarios:

  1. Preinstall needed resources through secure channels if possible. An example would be to customize your SageMaker AI image by installing dependencies, after they are code scanned, vetted technically and legally by your organization.
  2. If AWS PrivateLink integration is not available for external providers, allowlist network connections to these external sources. Allow firewall egress rules, directly or indirectly, through a proxy in your organization’s network. Check with your network administrator to understand the most appropriate option for your organization.

VPC Requirements

When setting up a new SageMaker Unified Studio Domain, it’s necessary to supply a VPC. It’s important to note that these VPC requirements are a union of all the requirements from the respective compute services integrated into Studio, some of which are reinforced by validation checks during the corresponding blueprint’s deployment. If these requirements that have validation checks are not fulfilled, the resource(s) contained in that blueprint may fail to create on project creation (on-create), or when creating the compute resource (on-demand). This section will present a summary of these requirements, as well as relevant documentation links from which they originate.

Subnet requirements for specific compute in a VPC

This section lists the compute services integrated in SageMaker Unified Studio that require VPC/subnets when provisioning the respective compute resources.

Compute Connections

Other Services

Requirements

  1. Number of subnets: At least two private subnets. This requirement comes from Redshift Serverless.
  2. Availability zones (AZs): At least two different AZs (for Regions with two AZs, two subnets are sufficient). This requirement comes from Redshift Serverless. For workgroups with Enhanced VPC Routing (EVR), you need three AZs.
  3. Free IPs per subnet: At least three Ips per subnet. This requirement comes from Redshift Serverless without EVR. For detailed IP addresses requirement with EVR enabled workgroups, refer to Serverless usage considerations. Three is a minimum and may not be enough for your needs. For example, EMR cluster creation will fail if no subnets with enough IPs are found in the VPC. We recommend doing a forward-looking capacity planning exercise based on your use cases (for example, growth rate, users, compute needs) to project at least 5 years into the future. This helps to determine how many IPs are needed by the team using Studio and other services that use this VPC and come up with a ceiling for the CIDR block size.
  4. Private or public subnets: We enforce that at least three private subnets be supplied, and recommend that only private subnets are chosen, with a few nuances. This requirement comes from SageMaker AI domain. A new SageMaker AI domain, when set up with VpcOnly mode, requires that all subnets in the VPC be private. This is the default networking mode in the Tooling blueprint. If you choose to use PublicInternetOnly mode, this restriction does not apply, you may choose public subnets from your VPC. To change the mode, modify the Tooling Blueprint parameter sagemakerDomainNetworkType.
  5. Enable DNS hostname and DNS Support: Both must be enabled. This requirement comes from EMR. Without these VPC settings, enableDnsHostname and enableDnsSupport, connecting to the EMR Cluster using the private DNS name through the Livy Endpoint will fail. SSL Verification, which can only be done when connecting using the DNS name, not the IP.
  6. Auto assign public IP: Disable. We recommend that this EC2 subnet setting (mapPublicIpOnLaunch) be disabled when using private subnets, because public IPs come at a cost and are a scarce resource in the total addressable IPv4 space.

VPC endpoints

If you choose to run SageMaker Unified Studio without public internet access, VPC endpoints are required for all services SageMaker Unified Studio needs to access. These endpoints provide secure, private connectivity between your VPC and AWS services without traversing the public internet. The following table lists the required endpoints, their types, and what each is used for.

Some endpoints may not show up directly in your browser’s network tab. The reason is that some of these services (such as CloudWatch) are transitively invoked by other services.

Mandatory endpoints

The following are required endpoints for SageMaker Unified Studio and supporting services to function properly. Gateway endpoints can be used where available, you can use interface endpoints for all other AWS services.

AWS service Endpoint Type Purpose
Glue
com.amazonaws.${region}.glue

Interface For Data Catalog and metadata management
STS
com.amazonaws.${region}.sts

Interface Required for assuming IAM roles
S3
com.amazonaws.${region}.s3

Gateway Required for datasets, Git backups, notebooks, and Git sync
SageMaker
com.amazonaws.${region}.sagemaker.api

Interface Required for calling SageMaker APIs
com.amazonaws.${region}.sagemaker.runtime

Interface For invoking deployed inference endpoints
DataZone
com.amazonaws.${region}.datazone

Interface For data catalog and governance
Secrets Manager
com.amazonaws.${region}.secretsmanager

Interface To securely access secrets
SSM
com.amazonaws.${region}.ssm

Interface For secure command execution
com.amazonaws.${region}.ssmmessages

Interface Enables live SSM sessions
KMS
com.amazonaws.${region}.kms

Interface For decrypting data (volumes, S3, secrets)
EC2
com.amazonaws.${region}.ec2

Interface For subnet and ENI management
com.amazonaws.${region}.ec2messages

Interface Required for SSM messaging
Athena
com.amazonaws.${region}.athena

Interface Required to run SQL queries
Amazon Q
com.amazonaws.${region}.q

Interface Used by SageMaker Notebooks for enhanced productivity

Optional Endpoints

Only create these if the corresponding service is used in your environment.

AWS service Endpoint Type Purpose
EMR
com.amazonaws.${region}.emr-serverless

Interface Serverless Spark/Hive jobs
com.amazonaws.${region}.emr-serverless-services.livy

Interface Required for Livy job submission (EMR Serverless)
com.amazonaws.${region}.elasticmapreduce

Interface Classic EMR (EC2-based)
com.amazonaws.${region}.emr-containers

Interface EMR on EKS workloads
Redshift
com.amazonaws.${region}.redshift

Interface For provisioned Redshift clusters
com.amazonaws.${region}.redshift-serverless

Interface For Redshift Serverless
com.amazonaws.${region}.redshift-data

Interface Required for running SQL against Redshift
Amazon Bedrock
com.amazonaws.${region}.bedrock-runtime

Interface Invoke Bedrock models at runtime
com.amazonaws.${region}.bedrock-agent

Interface For Bedrock knowledge agents
com.amazonaws.${region}.bedrock-agent-runtime

Interface For running knowledge agent workloads
CloudWatch
com.amazonaws.${region}.logs

Interface Application and notebook logs
RDS
com.amazonaws.${region}.rds

Interface Connect to Amazon RDS and Aurora
CodeCommit
com.amazonaws.${region}.codecommit

Interface Git integration with CodeCommit
com.amazonaws.${region}.git-codecommit

Interface Alternative endpoint for CodeCommit
CodeConnections and CodeStar
com.amazonaws.${region}.codeconnections.api

Interface GitHub and GitLab repo integration
com.amazonaws.${region}.codestar-connections.api

Interface Alias of CodeConnections

Clean up

AWS resources provisioned in your AWS accounts may incur costs based on the resources consumed. Make sure you do not leave any unintended resources provisioned. If you created a VPC and subsequent resources as part of this post, make sure you delete them.

The following service resources provisioned during this blog post need to be deleted:

  • IAM Identity Center users and groups.
  • Resources provisioned within your project using tooling configuration and blueprints within your domain.
  • The airgapped VPC.

Conclusion

In this post, we walked through the process of using your own existing VPC when creating domains and projects in SageMaker Unified Studio. This approach benefits customers by giving them greater control over their network infrastructure while using the comprehensive data, analytics, and AI/ML capabilities of Amazon SageMaker. We also explored the critical role of VPC endpoints in this set up. You now understand when these become necessary components of your architecture, particularly in scenarios requiring enhanced security, compliance with data residency requirements, or improved network performance.

While using a custom VPC requires more initial set up than the Quick Create option, it provides the flexibility and control many organizations need for their data science and analytics workflows. This approach provides a mechanism for your SageMaker environment to integrate with your existing infrastructure and adheres to your organization’s networking policies. Custom VPC configurations are a powerful tool in your arsenal for building secure, compliant, and efficient data science environments.

To learn more, visit Amazon SageMaker Unified Studio – Administrator Guide and User Guide.


About the authors

Saurabh Bhutyani

Saurabh Bhutyani

Saurabh is a Principal Analytics Specialist Solutions Architect at AWS. He is passionate about new technologies. He joined AWS in 2019 and works with customers to provide architectural guidance for running generative AI use cases, scalable analytics solutions and data mesh architectures using AWS services like Amazon Bedrock, Amazon SageMaker, Amazon EMR, Amazon Athena, AWS Glue, AWS Lake Formation, and Amazon DataZone.

Rohit Vashishtha

Rohit Vashishtha

Rohit is a Senior Analytics Specialist Solutions Architect at AWS based in Dallas, Texas. He has two decades of experience architecting, building, leading, and maintaining big data platforms. Rohit helps customers modernize their analytic workloads using the breadth of AWS services and ensures that customers get the best price/performance with utmost security and data governance.

Baggio Wong

Baggio is a Software Engineer on the SageMaker Unified Studio team, where he designs and delivers experiences that empower data practitioners to build and deploy AI/ML workloads.

Navigating multi-account deployments in Amazon SageMaker Unified Studio: a governance-first approach

Post Syndicated from Ben Shafabakhsh original https://aws.amazon.com/blogs/big-data/navigating-multi-account-deployments-in-amazon-sagemaker-unified-studio-a-governance-first-approach/

Amazon SageMaker Unified Studio brings together data engineering, analytics, and machine learning (ML) workflows into a cohesive, governed environment. This unified approach reduces traditional silos between data teams and ML practitioners, so organizations can advance their AI and ML initiatives with greater collaboration and efficiency.

As enterprises begin their SageMaker Unified Studio adoption, they must determine the best practices for implementing data federation principles when using SageMaker Unified Studio across the organization. The way that you structure your SageMaker Unified Studio deployment is more than a technical decision. It directly impacts your governance framework, security posture, operational scalability, and day-to-day team collaboration.

In this post, we explore SageMaker Unified Studio multi-account deployments in depth: what they entail, why they matter, and how to implement them effectively. We examine architecture patterns, evaluate trade-offs across security boundaries, operational overhead, and team autonomy. We also provide practical guidance to help you design a deployment that balances centralized control with distributed ownership across your organization.

The multi-account challenge: why organizations struggle

If you’re working in a large enterprise, a multi-account AWS environment is often your starting position. If you’re starting from scratch, consider whether to use a single-account for all SageMaker Unified Studio components or dedicate separate accounts for governance and business units. A multi-account architecture aligns with AWS best practices and proves valuable if you have:

  • Distributed teams with independent operations: multi-account architecture accommodates multiple teams or business units that maintain separate operations so that each team can manage their projects autonomously within isolated environments. Each unit can deploy and manage resources independently, implement team-specific security controls, and scale infrastructure without impacting others. This is achieved through a shared, unified integrated development environment (IDE) for collaboration and standardized tools across the organization.
  • Compliance and data governance requirements: For regulatory mandates like GDPR, HIPAA, or data sovereignty needs, you will benefit from this setup, because sensitive data remains segregated in business-unit specific accounts. This reduces risk exposure, streamlines audits, and maintains compliance boundaries without compromising access to centralized collaboration tools.
  • Centralized governance: A multi-account architecture maintains visibility across all projects and business units from a single control plane. The Domain account can enforce security policies and compliance requirements across the entire organization and provide centralized monitoring, audit logging, and user access management.
  • Clear cost visibility and accountability: Multi-account architecture enables granular billing tracking, with each account generating separate bills that clearly attribute costs to specific teams or business units. This transparency streamlines budgeting and financial accountability, removing the complexity of cost allocation tags and manual reporting that’s typically required in single-account models where multiple teams share the same infrastructure and resources.

Overall, this approach improves efficiency, security, and scalability for you, whether you’re managing a few teams or coordinating across a larger organizational structure.

Understanding the core constructs of SageMaker Unified Studio

Before diving into multi-account strategies, it’s important to understand the foundational constructs of SageMaker Unified Studio. Each is elaborated in greater detail in the Administrator Guide.

  • Domain: The top-level administrative boundary where governance lives. In a multi-account setup, this is your centralized control plane for catalog, policies, and user access.
  • Project: A collaborative workspace for developing data, AI, and ML initiatives. In multi-account deployments, a Project’s metadata lives in the Domain account and compute and data resources deploy into associated business unit accounts. This separation is central to the pattern that we explore.
  • Project Profile: A template that standardizes how Projects are created. For multi-account setups, this is where administrators define which accounts and AWS Regions Projects can target.
  • Blueprints: Infrastructure as code (IaC) components that define what gets provisioned inside a Project. Each associated account must enable its relevant Blueprints before Projects can deploy there.

The following diagram illustrates how these key constructs interact. Within a Domain, users create Projects organized through a single Project Profile. The Project Profile defines and configures a collection of Blueprints. When a project is created, the infrastructure specified in those Blueprints is automatically provisioned and becomes available within the project workspace.

SageMaker Unified Studio Domain architecture diagram demonstrating blueprint management and infrastructure deployment workflow. This technical diagram illustrates how AWS SageMaker projects utilize enabled blueprints through profile configuration to deploy infrastructure resources. The workflow shows Project ABC with People, Data/Code, and Compute/Resources components connecting to Project Profile X, which filters enabled blueprints (Tooling Blueprint and X Blueprint) for deployment while excluding disabled blueprints (Y Blueprint and Z Blueprint). The deployed infrastructure section displays the resulting Tooling Blueprint Infrastructure and X Blueprint Infrastructure as purple cube icons, representing the final deployed resources in the SageMaker environment.
Figure 1: Amazon SageMaker Unified Studio Core Constructs

Multi-account setup in SageMaker Unified Studio

To illustrate these concepts in practice, we demonstrate with a sample enterprise organization that exemplifies enterprise environments with several AWS accounts belonging to different business units:

  • Central Data Governance team: Owns and manages governance and access control across the organization. They plan to build a data solution in a dedicated AWS account using SageMaker Unified Studio. The platform must provide an integrated development environment (IDE) to work with data and ML use cases and connect to multiple business unit’s AWS accounts (Finance and Marketing).
  • Finance Business Unit: Owns datasets for fraud analysis and churn prediction in their own AWS account.
  • Marketing Business Unit: Maintains customer sentiment data and campaign analytics in their own AWS account.

In the following diagram we show the Data platform constructs provided by SageMaker Unified Studio in each AWS account showing the clear separation between centralized governance and distributed resource deployment.

AWS multi-account data governance architecture diagram illustrating centralized policy management with distributed departmental execution. This enterprise architecture shows how a Central Data Governance Team maintains standards across multiple AWS accounts. The Central Data Governance Account serves as the control plane, housing the Domain with Platform Resources (Catalog and Shared infrastructure), Governance Constructs (Domain Units and Metadata Forms), and Governance Policies (Authorization Policies and Enforcement). Marketing Teams and Finance Teams access their respective projects within the central governance framework, which then connect to separate Marketing and Finance AWS accounts. Each departmental account maintains its own Resources and Data infrastructure while adhering to centralized governance standards, enabling federated data management with consistent oversight across the organization.

Figure 2: Sample organization architecture in Amazon SageMaker Unified Studio

The Central Data Governance Account contains the SageMaker Unified Studio Domain. This contains the shared platform resources (Catalog, shared infrastructure), governance constructs (Domain units, metadata forms), and governance policies (authorization policies, enforcement rules). These configuration elements define the standards and capabilities available across the organization. They’re the Service-level configuration data: Metadata, policies, and governance rules that define how resources should be provisioned.

In contrast, the Associated Accounts (Marketing and Finance) contain the actual AWS infrastructure, compute/storage (purple cubes) and data stores (cylinders), provisioned when Projects are created. The diagram shows how Marketing Projects and Finance Projects ultimately deploy their runtime resources into their respective business unit accounts. The separation keeps the governance centralized and consistent while allowing business unit dependent resources to be isolated, billed separately, and managed according to each business unit’s specific requirements.

To understand the core constructs of SageMaker Unified Studio, we listed the core components of SageMaker Unified Studio and explained how they relate to each other. Taking the same diagram as the basis, we will now represent how these constructs are created in our multi-account sample scenario.

Construct Deployment Location Deployed Resources
Domain Central Data Governance Account
  • Portal
  • Catalog
  • Metadata Forms
  • Authorization Policies
Project Central Data Governance Account + Associated Account In Central Data Governance Account:

  • Project configuration and metadata

In Associated Account:

  • Project Infrastructure resources such as Compute
  • Project Data
Project Profile Central Data Governance Account
  • Project Profile Configuration
Blueprint Associated Account
  • Blueprints are enabled in each associated account

Core construct deployment locations and resources in SageMaker Unified Studio

Implementing multi-account deployments

To enable production-ready data science and analytics workflows across multiple AWS accounts governed by a SageMaker Unified Studio Domain, organizations must establish a structured cross-account configuration. This setup allows each business unit (BU) to retain ownership of its Projects and AWS resources while using centralized governance provided by the Domain. The process involves four key steps: account association, Blueprint enablement, Project Profile configuration, and Project creation.

Note: The following steps provide a high-level overview of the multi-account deployment process. For a more detailed, step-by-step guide, refer to How to associate an account when using Amazon SageMaker Unified Studio.

Step 1: Account association to a domain

The Domain administrator associates each AWS account with the SageMaker Unified Studio Domain for seamless cross-account functionality by providing the AWS account number for the targeted accounts. This association lets the Domain publish and consume data from associated accounts, create resources within them, maintain cross-account access for the SageMaker Catalog, and deploy Projects directly into business unit accounts. Account association is a critical prerequisite for cross-account Project deployment. Behind the scenes, SageMaker Unified Studio uses AWS Resource Access Manager (AWS RAM) to make this cross-account functionality happen.

Step 2: Enabling blueprints

Each associate account administrator must enable the relevant Blueprints before creating Project Profiles. This important step verifies that Projects can provision the necessary tools and resources that users need to run their workloads. Blueprints serve as standardized infrastructure templates that administrators can use to enforce organizational standards, security controls, and best practices across all Projects. Through Blueprints, administrators configure essential resources including AWS Identity and Access Management (IAM) roles, AWS Key Management Service (AWS KMS) keys, Amazon Simple Storage Service (Amazon S3) buckets, Amazon Virtual Private Cloud (Amazon VPC) settings, and security groups. This centralized approach helps maintain consistency, compliance, and governance at scale while preventing users from creating Projects with misconfigured or non-compliant infrastructure.

Step 3: Configuring project profile

With the accounts successfully associated and the Blueprints enabled, the next step is to configure a Project Profile that determines where your Project resources will be deployed. Your choice of Project Profile strategy impacts both operational flexibility and governance.

Domain administrators control which Blueprints are included in each Project Profile and can specify the target AWS Regions and accounts for deployment, providing the governance foundation to standardize Project creation. Administrators can use pre-created Project Profiles like “All Capabilities” or “SQL Analytics”, or create custom Project Profiles tailored to specific organizational needs.

When configuring Project Profiles, you can choose between two deployment models:

  • Static (Pre-Defined): Profile specifies a fixed account and Region. Projects by default deploy to the same location. This is recommended for strict governance controls and compliance requirements where production resources must remain in designated accounts or Regions.
  • Dynamic (Parameterized): Users select from available associated accounts and Regions during Project creation (configured through Account Pools). This is recommended for multi-environment workflows (Dev/Test/Prod) and reducing administrative overhead by maintaining fewer profile templates.

Dynamic profiles balance governance with agility: Administrators define standards once, while users retain deployment flexibility aligned with their business needs.

Step 4: Project creation

With Project Profiles configured, you can now create a new Project from any of the associated accounts using the profile created in the previous step.

Defining project boundaries: when to create a new project

One of the common challenges that you will face is determining when to create a new Project. The answer significantly impacts collaboration effectiveness, resource isolation, cost tracking, and governance. Here’s a practical framework to guide your decision-making.

A Project should represent a distinct business initiative with a defined scope, a dedicated team, and measurable outcomes. Think of Projects as team workspaces organized around business outcomes, not technical components.

Create a new Project when you need clear separation across multiple dimensions: cost allocation, access control, and data governance. If Finance and Marketing teams require separate budget tracking, distinct data access policies, and different governance controls, they should have separate Projects. For example, “Customer Churn Prediction” and “Fraud Detection” might use similar tools, but if they have different stakeholders, budget owners, and data sensitivity requirements, so they warrant separation. Similarly, create separate Projects when facing different compliance or regulatory requirements (like HIPAA versus PCI-DSS) or when initiatives have independent deployment lifecycles. Experimental ML research Projects shouldn’t share workspaces with production recommendation engines that require stricter change controls and availability guarantees.

However, avoid fragmenting related work into unnecessary silos:

  • Don’t create separate Projects for individual workflows or pipelines, a single “Marketing Campaign Optimization” Project should contain audience segmentation, propensity modeling, and campaign attribution workflows together.
  • Don’t separate different data processing stages; keep data ingestion, transformation, and analysis within one Project to maintain clear lineage and enable seamless collaboration.
  • Projects are team workspaces, not personal sandboxes, so use shared Projects with role-based access control rather than creating individual Projects per team member.
  • Small proof of concepts (POC) or temporary experiments should be conducted within the parent Project, with successful initiatives promoted to dedicated production Projects only when they mature into full-scale capabilities requiring independent governance.

Conclusion

Throughout this post, we explored how the separation of governance and working accounts forms the foundation of a scalable, secure, and compliant data and AI platform.

With centralized governance in the Domain account, organizations can enforce consistent security policies, compliance requirements, and cost management, while allowing sub-accounts the autonomy over their own resources. This approach enhances security and compliance, and fosters collaboration and innovation within teams by providing them with the flexibility that they need to operate effectively. Ultimately, this governance-first strategy supports keeping data remains protected and accessible in a controlled manner, empowering teams to drive business outcomes efficiently. To implement a multi-account deployment for your organization, get started by creating your first SageMaker Unified Studio Domain and follow the step-by-step guidance to establish your governance-first architecture.


About the authors

Ben Shafabakhsh

Ben Shafabakhsh

Ben is a Partner Solution Architect at AWS. He works with AWS consulting and system integrator partners in building technology solutions and implementing strategies to drive adoption of AWS services.

Adriana Lopez

Adriana Lopez

Adriana is a Software Development Engineer at AWS Professional Services. She is passionate about data and AI governance, focusing on building ingenious solutions that empower teams with the data and AI agents and tools they need to innovate.

Juan Daza

Juan Daza

Juan is a Senior Delivery Consultant for Data & Analytics at AWS Professional Services. He specializes in the design, development, and deployment of modern data and analytics platforms. His work focuses on data governance and architecting AI-ready data systems.