The 6.15 merge window saw the inclusion of a new type of lock for BPF programs:
a resilient queued spinlock that Kumar Kartikeya Dwivedi has been working on
for some time. Eventually, he hopes to convert all of the spinlocks currently
used in the BPF subsystem to his new lock.
He gave a remote presentation about the design of the lock at the
2025 Linux Storage, Filesystem,
Memory-Management, and BPF summit.
Over the past few years, we’ve seen developers push the boundaries of what’s possible with real-time communication — tools for collaborative work, massive online watch parties, and interactive live classrooms are all exploding in popularity.
We use AI more and more in our daily lives. Text-based interactions are evolving into something more natural: voice and video. When users interact with the applications and tools that AI developers create, we have high expectations for response time and connection quality. Complex applications of AI are built on not just one tool, but a combination of tools, often from different providers which requires a well connected cloud to sit in the middle for the coordination of different AI tools.
Developers already use Workers, Workers AI, and our WebRTC SFU and TURN services to build powerful apps without needing to think about coordinating compute or media services to be closest to their user. It’s only natural for there to be a singular “Region: Earth” for real-time applications.
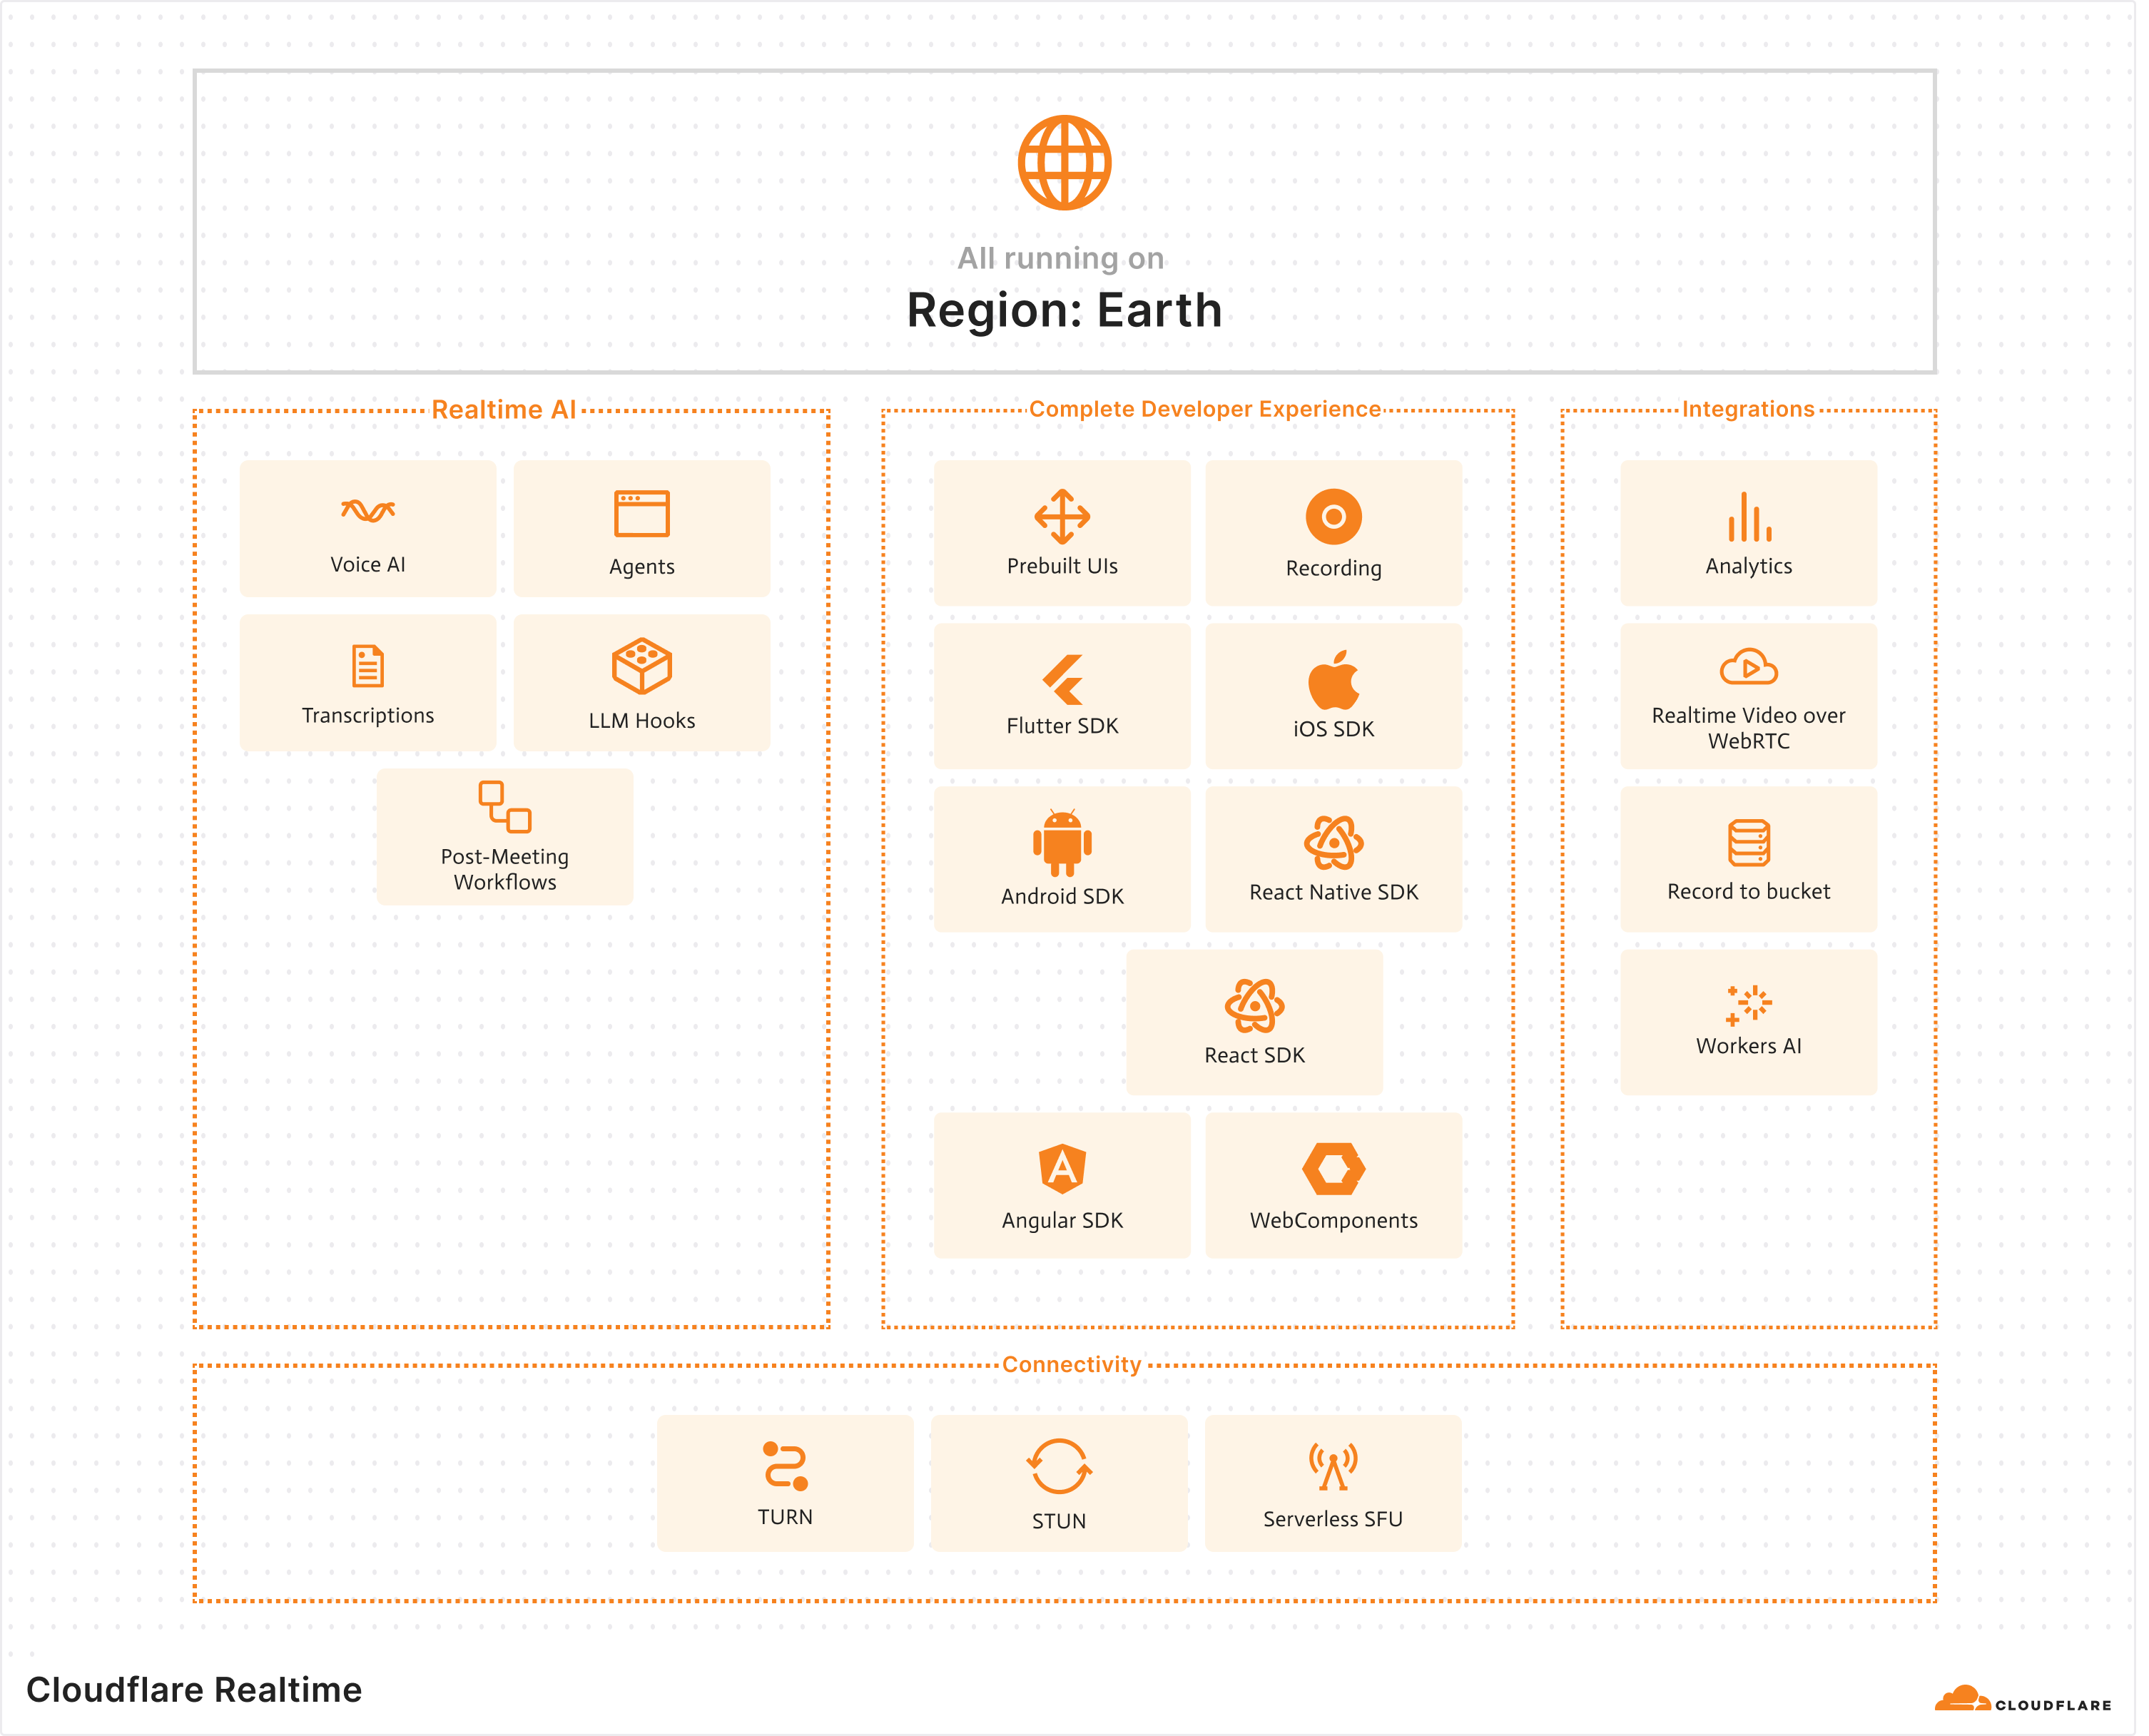
We’re excited to introduce Cloudflare Realtime — a suite of products to help you make your apps truly interactive with real-time audio and video experiences. Cloudflare Realtime now brings together our SFU, STUN, and TURN services, along with the new RealtimeKit.
Say hello to RealtimeKit
RealtimeKit is a collection of mobile SDKs (iOS, Android, React Native, Flutter), SDKs for the Web (React, Angular, vanilla JS, WebComponents), and server side services (recording, coordination, transcription) that make it easier than ever to build real-time voice, video, and AI applications. RealtimeKit also includes user interface components to build interfaces quickly.
The amazing team behind Dyte, a leading company in the real-time ecosystem, joined Cloudflare to accelerate the development of RealtimeKit. The Dyte team spent years focused on making real-time experiences accessible to developers of all skill levels, and had a deep understanding of the developer journey — they built abstractions that hid WebRTC’s complexity without removing its power.
Already a user of Cloudflare’s products, Dyte was a perfect complement to Cloudflare’s existing real-time infrastructure spanning 300+ cities worldwide. They built a developer experience layer that made complex media capabilities accessible. We’re incredibly excited for their team to join Cloudflare as we help developers define the future of user interaction for real-time applications as one team.
For many developers, what starts as “let’s add video chat” can quickly escalate into weeks of technical deep dives into WebSockets and WebRTC. While we are big believers in the potential of WebRTC, we also know that it comes with real challenges when building for the first time. Debugging WebRTC sessions can require developers to learn about esoteric new concepts such as navigating ICE candidate failures, TURN server configurations, and SDP negotiation issues.
The challenges of building a WebRTC app for the first time don’t stop there. Device management adds another layer of complexity. Inconsistent camera and microphone APIs across browsers and mobile platforms introduce unexpected behaviors in production. Chrome handles resolution switching one way, Safari another, and Android WebViews break in uniquely frustrating ways. We regularly see applications that function perfectly in testing environments fail mysteriously when deployed to certain devices or browsers.
Systems that work flawlessly with 5 test users collapse under the load of 50 real-world participants. Bandwidth adaptation falters, connection management becomes unwieldy, and maintaining consistent quality across diverse network conditions proves nearly impossible without specialized expertise.
What starts as a straightforward feature becomes a multi-month project requiring low-level engineering to solve problems that aren’t core to your business.
We realized that we needed to extend our products to client devices to help solve these problems.
RealtimeKit SDKs for Kotlin, React Native, Swift, JavaScript, Flutter
RealtimeKit is our toolkit for building real-time applications without common WebRTC headaches. The core of RealtimeKit is a set of cross-platform SDKs that handle all the low-level complexities, from session establishment and media permissions to NAT traversal and connection management. Instead of spending weeks implementing and debugging these foundations, you can focus entirely on creating unique experiences for your users.
Recording capabilities come built-in, eliminating one of the most commonly requested yet difficult-to-implement features in real-time applications. Whether you need to capture meetings for compliance, save virtual classroom sessions for students who couldn’t attend live, or enable content creators to archive their streams, RealtimeKit handles the entire media pipeline. No more wrestling with MediaRecorder APIs or building custom recording infrastructure — it just works, scaling alongside your user base.
We’ve also integrated voice AI capabilities from providers like ElevenLabs directly into the platform. Adding AI participants to conversations becomes as simple as a function call, opening up entirely new interaction models. These AI voices operate with the same low latency as human participants — tens of milliseconds across our global network — creating truly synchronous experiences where AI and humans converse naturally. Combined with RealtimeKit’s ability to scale to millions of concurrent participants, this enables entirely new categories of applications that weren’t feasible before.
The Developer Experience
RealtimeKit focuses on what developers want to accomplish, rather than how the underlying protocols work. Adding participants or turning on recording are just an API call away. SDKs handle device enumeration, permission requests, and UI rendering across platforms. Behind the scenes, we’re solving the thorny problems of media orchestration and state management that can be challenging to debug.
We’ve been quietly working towards launching the Cloudflare RealtimeKit for years. From the very beginning, our global network has been optimized for minimizing latency between our network and end users, which is where the majority of network disruptions are introduced.
We developed a Selective Forwarding Unit (SFU) that intelligently routes media streams between participants, dynamically adjusting quality based on network conditions. Our TURN infrastructure solves the complex problem of NAT traversal, allowing connections to be established reliably behind firewalls. With Workers AI, we brought inference capabilities to the edge, minimizing latency for AI-powered interactions. Workers and Durable Objects provided the WebSockets coordination layer necessary for maintaining consistent state across participants.
SFU and TURN services are now Generally Available
We’re also announcing the General Availability of our SFU and TURN services for WebRTC developers that need more control and a low-level integration with the Cloudflare network.
SFU now supports simulcast, a very common feature request. Simulcast allows developers to select media streams from multiple options, similar to selecting the quality level of an online video, but for WebRTC. Users with different network qualities are now able to receive different levels of quality, either automatically defined by the SFU or manually selected.
Our TURN service now offers advanced analytics with insight into regional, country, and city level usage metrics. Together with Custom Identifiers, and revocable tokens, Cloudflare’s TURN service offers an in-depth view into usage and helps avoid abuse.
Our SFU and TURN products continue to be one of the most affordable ways to build WebRTC apps at scale, at 5 cents per GB after 1,000 GB of free usage each month.
Partnering with Hugging Face to make realtime AI communication seamless
FastRTC is a lightweight Python library from Hugging Face that makes it easy to stream real-time audio and video into and out of AI models using WebRTC. TURN servers are a critical part of WebRTC infrastructure and ensure that media streams can reliably connect across firewalls and NATs. For users of FastRTC, setting up a globally distributed TURN server can be complex and expensive.
Through our new partnership with Hugging Face, FastRTC users now have free access to Cloudflare’s TURN Server product, giving them reliable connectivity out of the box. Developers get 10 GB of TURN bandwidth each month using just a Hugging Face access token — no setup, no credit card, no servers to manage. As projects grow, they can easily switch to a Cloudflare account for more capacity and a larger free tier.
This integration allows AI developers to focus on building voice interfaces, video pipelines, and multimodal apps without worrying about NAT traversal or network reliability. FastRTC simplifies the code, and Cloudflare ensures it works everywhere. See these demos to get started.
Ship AI-powered realtime apps in days, not weeks
With RealtimeKit, developers can now implement complex real-time experiences in hours. The SDKs abstract away the most time-consuming aspects of WebRTC development while providing APIs tailored to common implementation patterns. Here are a few of the possibilities:
Video conferencing: Add multi-participant video calls to your application with just a few lines of code. RealtimeKit handles the connection management, bandwidth adaptation, and device permissions that typically consume weeks of development time.
Live streaming: Build interactive broadcasts where hosts can stream to thousands of viewers while selectively bringing participants on-screen. The SFU automatically optimizes media routing based on participant roles and network conditions.
Real-time synchronization: Implement watch parties or collaborative viewing experiences where content playback stays synchronized across all participants. The timing API handles the complex delay calculations and adjustments traditionally required.
Voice AI integrations: Add transcription and AI voice participants without building custom media pipelines. RealtimeKit’s media processing APIs integrate with your existing authentication and storage systems rather than requiring separate infrastructure.
When we’ve seen our early testers use the RealtimeKit, it doesn’t just accelerate their existing projects, it fundamentally changes which projects become viable.
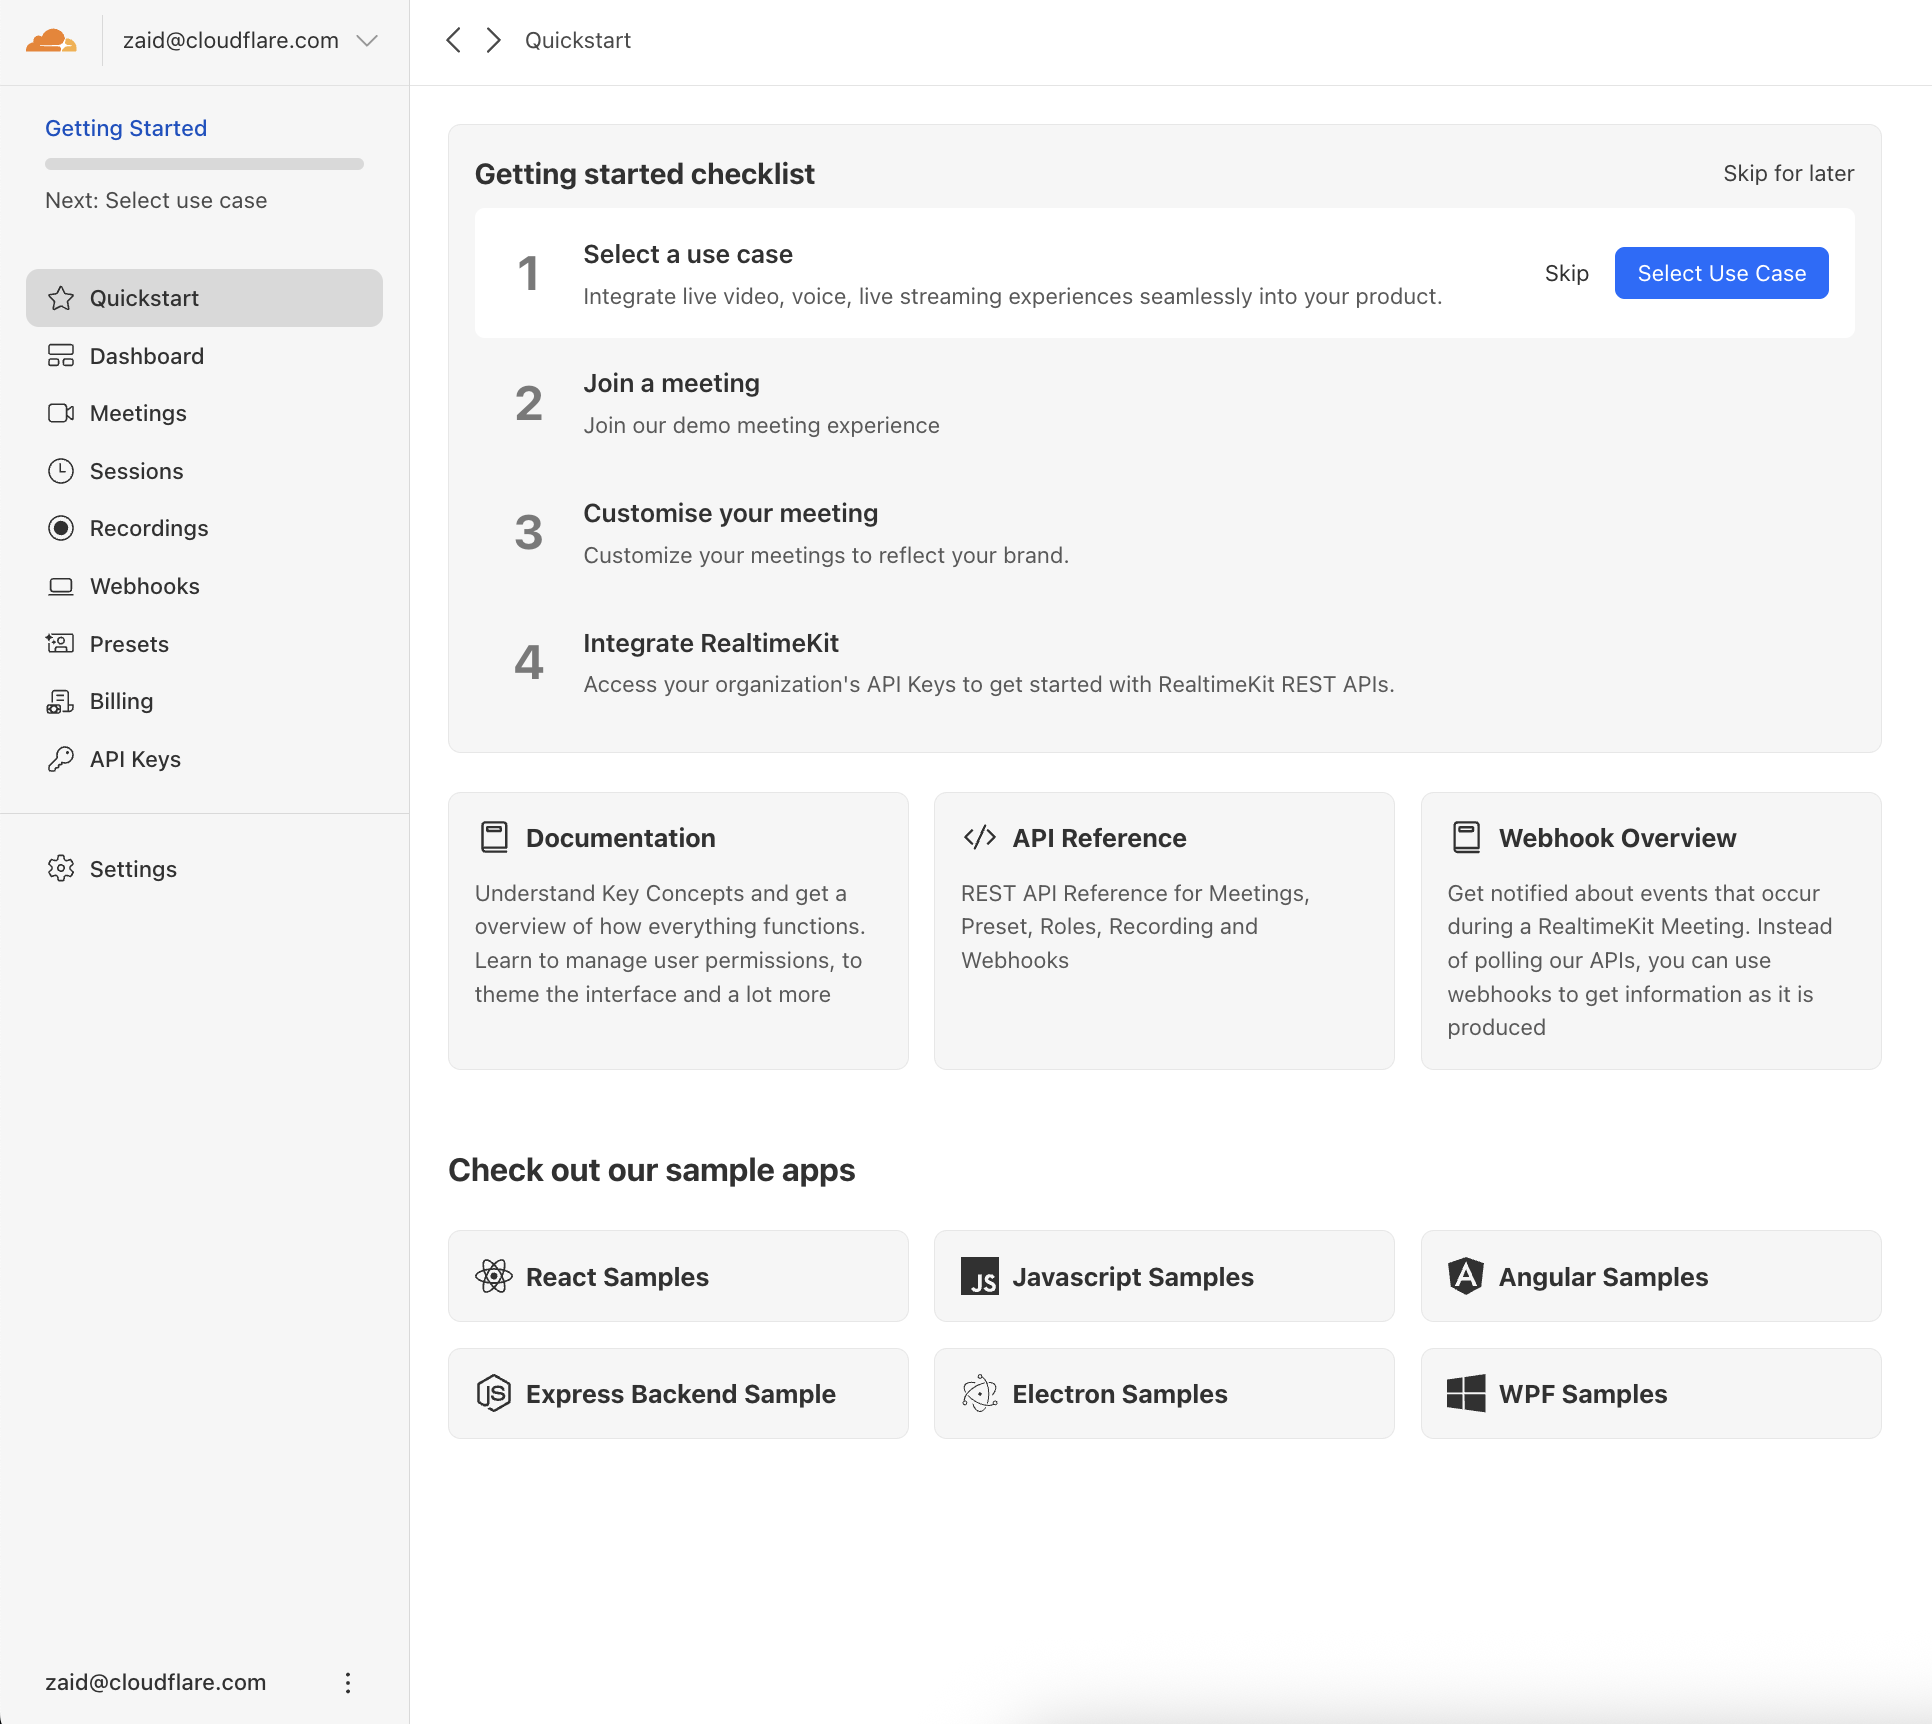
RealtimeKit is currently in a closed beta ready for select customers to start kicking the tires. There is currently no cost to test it out during the beta. Request early access here or via the link in your Cloudflare dashboard. We can’t wait to see what you build.
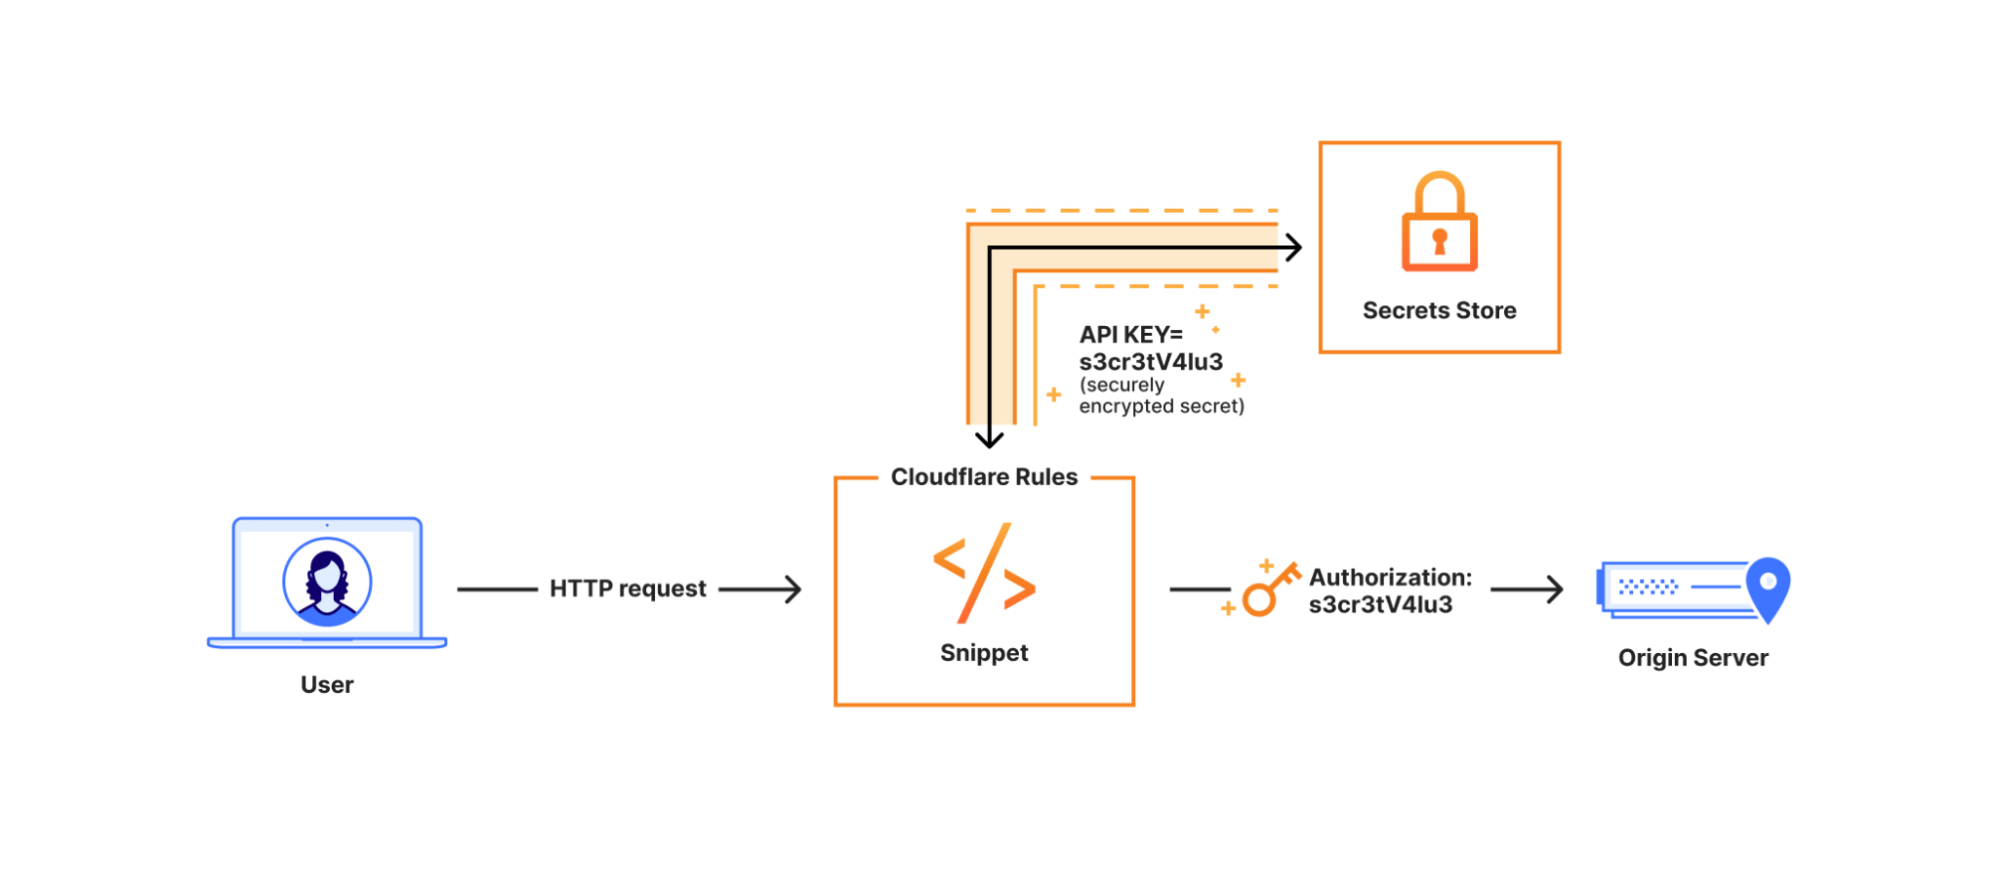
Every cloud platform needs a secure way to store API tokens, keys, and credentials — welcome, Cloudflare Secrets Store! Today, we are very excited to announce and launch Secrets Store in beta. We built Cloudflare Secrets Store to help our customers centralize management, improve security, and restrict access to sensitive values on the Cloudflare platform.
Wherever secrets exist at Cloudflare – from our developer platform, to AI products, to Cloudflare One – we’ve built a centralized platform that allows you to manage them in one place.
We are excited to integrate Cloudflare Secrets Store with the whole portfolio of Cloudflare products, starting today with Cloudflare Workers.
Securing your secrets across Workers
If you have a secret you want to use across multiple Workers, you can now use the Cloudflare Secrets Store to do so. You can spin up your store from the dashboard or by using Wrangler CLI:
wrangler secrets-store store create <name>
Then, create a secret:
wrangler secrets-store secret create <store-id>
Once the secret is created, you can specify the binding to deploy in a Worker immediately.
Last step – you can now reference the secret in code!
const openAIkey = await env.open_AI_key.get();
Environment variables and secrets were first launched in Cloudflare Workers back in 2020. Now, there are millions of local secrets deployed on Workers scripts. However, these are not all unique. Many of these secrets have duplicate values within a customer’s account. For example, a customer may reuse the same API token in ten different scripts, but since each secret is accessible only on the per-Worker level, that value would be stored in ten different local secrets. Plus, if you need to roll that secret, there is no seamless way to do so that preserves a single source of truth.
With thousands of secrets duplicated across scripts — each requiring manual creation and updates — scoping secrets to individual Workers has created significant friction for developers. Additionally, because Workers secrets are created and deployed locally, any secret is accessible – in terms of creation, editing, and deletion – to anyone who has access to that script.
Now, you can create account-level secrets and variables that can be shared across all Workers scripts, centrally managed and protected within the Secrets Store.
Building a secure secrets manager
The most important feature of a Secret Store, of course, is to make sure that your secrets are stored securely.
Once the secret is created, its value will not be readable by anyone, be it developers, admins, or Cloudflare employees. Only the permitted service will be able to use the value at runtime.
This is why the first thing that happens when you deploy a new secret to Cloudflare is encrypting the secret prior to storing it in our database. We make sure your tokens are safe and protected using a two-level key hierarchy, where the root key never leaves a secure system. This is done by making use of DEKs (Data Encryption Keys) to encrypt your secrets and a separate KEK (Key Encryption Key) to encrypt the DEKs themselves. The data encryption keys are refreshed frequently, making the possibility and impact scope of a single DEK exposure very small. In the future, we will introduce periodic key rotations for our KEK and also provide a way for customers to have their own account-specific DEKs.
After the secrets are encrypted, there are two permissions checks when deploying a secret from the Secrets Store to a Worker. First, the user must have sufficient permissions to create the binding. Second, when the Worker makes a fetch call to retrieve the secret value, we verify that the Worker has an appropriate binding to access that secret.
The secrets are automatically propagated across our network using Quicksilver – so that every secret is on every server– to ensure they’re immediately accessible and ready for the Worker to use. Wherever your Worker is deployed, your secrets will be, too.
If you’d like to use a secret to secure your AI model keys before passing on to AI Gateway:
export default {
 async fetch(request, env, ctx) {
   const prompt = "Write me a pun about Cloudflare";
   const openAIkey = await env.open_AI_key.get();

   const response = await fetch("https://gateway.ai.cloudflare.com/v1/YOUR_ACCOUNT_TAG/openai/chat/completions", {
     method: "POST",
     headers: {
       "Content-Type": "application/json",
       "Authorization": `Bearer ${openAIkey}`,
     },
     body: JSON.stringify({
       model: "gpt-3.5-turbo",
       messages: [
         { role: "user", content: prompt }
       ],
       temperature: 0.8,
       max_tokens: 100,
     }),
   });

   const data = await response.json();
   const answer = data.choices?.[0]?.message?.content || "No pun found 😢";

   return new Response(answer, {
     headers: { "Content-Type": "text/plain" },
   });
 }
};
Cloudflare Secrets Store, with built-in RBAC
Now, a secret’s value can be updated once and applied everywhere — but not by everyone. Cloudflare Secrets Store uses role-based access control (RBAC) to ensure that only those with permission can view, create, edit, or delete secrets. Additionally, any changes to the Secrets Store are recorded in the audit logs, allowing you to track changes.
Whereas per-Worker secrets are tied to the Workers account role, meaning that anyone who can modify the Worker can modify the secret, access to account-level secrets is restricted with more granular controls. This allows for differentiation between security admins who manage secrets and developers who use them in the code.
Secrets Store Admin
Secrets Store Reporter
Secrets Store Deployer
Create secrets
✓
Update secrets
✓
Delete secrets
✓
View secrets metadata
✓
✓
✓
Deploy secrets (i.e. bind to a Worker)
✓
Each secret can also be scoped to a particular Cloudflare product to ensure the value is only used where it is meant to be. Today, the secrets are restricted to Workers by default, but once the Secrets Store supports multiple products, you’ll be able to specify where the secret can be used (e.g. “I only want this secret to be accessible through Firewall Rules”).
What’s next for Secrets Store
Secrets Store will support all secrets across Cloudflare, including:
Cloudflare Access has service tokens to authenticate against your Zero Trust policies.
Transform Rules require sensitive values in the request headers to grant access or pass onto to something else.
AI Gateway relies upon secret keys from each provider to position Cloudflare between the end user and the AI model.
…and more!
Right now, to use a secret within a Worker, you have to create a binding for that specific secret. In the future, we’ll allow you to create a binding to the store itself so that the Worker can access any secret within that store. We’ll also allow customers to create multiple secret stores within their account so that they can manage secrets by group when creating access policies.
Every Cloudflare account can create up to twenty secrets for free. We’re currently finalizing our pricing and will publish more details for each tier soon.
We’re thrilled to get Secrets Store into our customers’ hands and are excited to continue building it out to support more products and features as we work towards making Secrets Store GA.
Program your traffic at the edge — fast, flexible, and free
Cloudflare Snippets are now generally available (GA) for all paid plans, giving you a fast, flexible way to control HTTP traffic using lightweight JavaScript “code rules” — at no extra cost.
Need to transform headers dynamically, fine-tune caching, rewrite URLs, retry failed requests, replace expired links, throttle suspicious traffic, or validate authentication tokens? Snippets provide a production-ready solution built for performance, security, and control.
With GA, we’re introducing a new code editor to streamline writing and testing logic. This summer, we’re also rolling out an integration with Secrets Store — enabling you to bind and manage sensitive values like API keys directly in Snippets, securely and at scale.
What are Snippets?
Snippets bring the power of JavaScript to Cloudflare Rules, letting you write logic that runs before a request reaches your origin or after a response returns from upstream. They’re ideal when built-in rule actions aren’t quite enough. While Cloudflare Rules let you define traffic logic without code, Snippets extend that model with greater flexibility for advanced scenarios.
Automated deployment and versioning via Terraform.
Best of all? Snippets are included at no extra cost for Pro, Business, and Enterprise plans — with no usage-based fees.
The journey to GA: How Snippets became production-grade
Cloudflare Snippets started as a bold idea: bring the power of JavaScript-based logic to Cloudflare Rules, without the complexity of a full-stack developer platform.
Over the past two years, Snippets have evolved into a production-ready “code rules” solution, shaping the future of HTTP traffic control.
2022: Cloudflare Snippets were announced during Developer Week as a solution for users needing flexible HTTP traffic modifications without a full Worker.
2023:Alpha launch — hundreds of users tested Snippets for high-performance traffic logic.
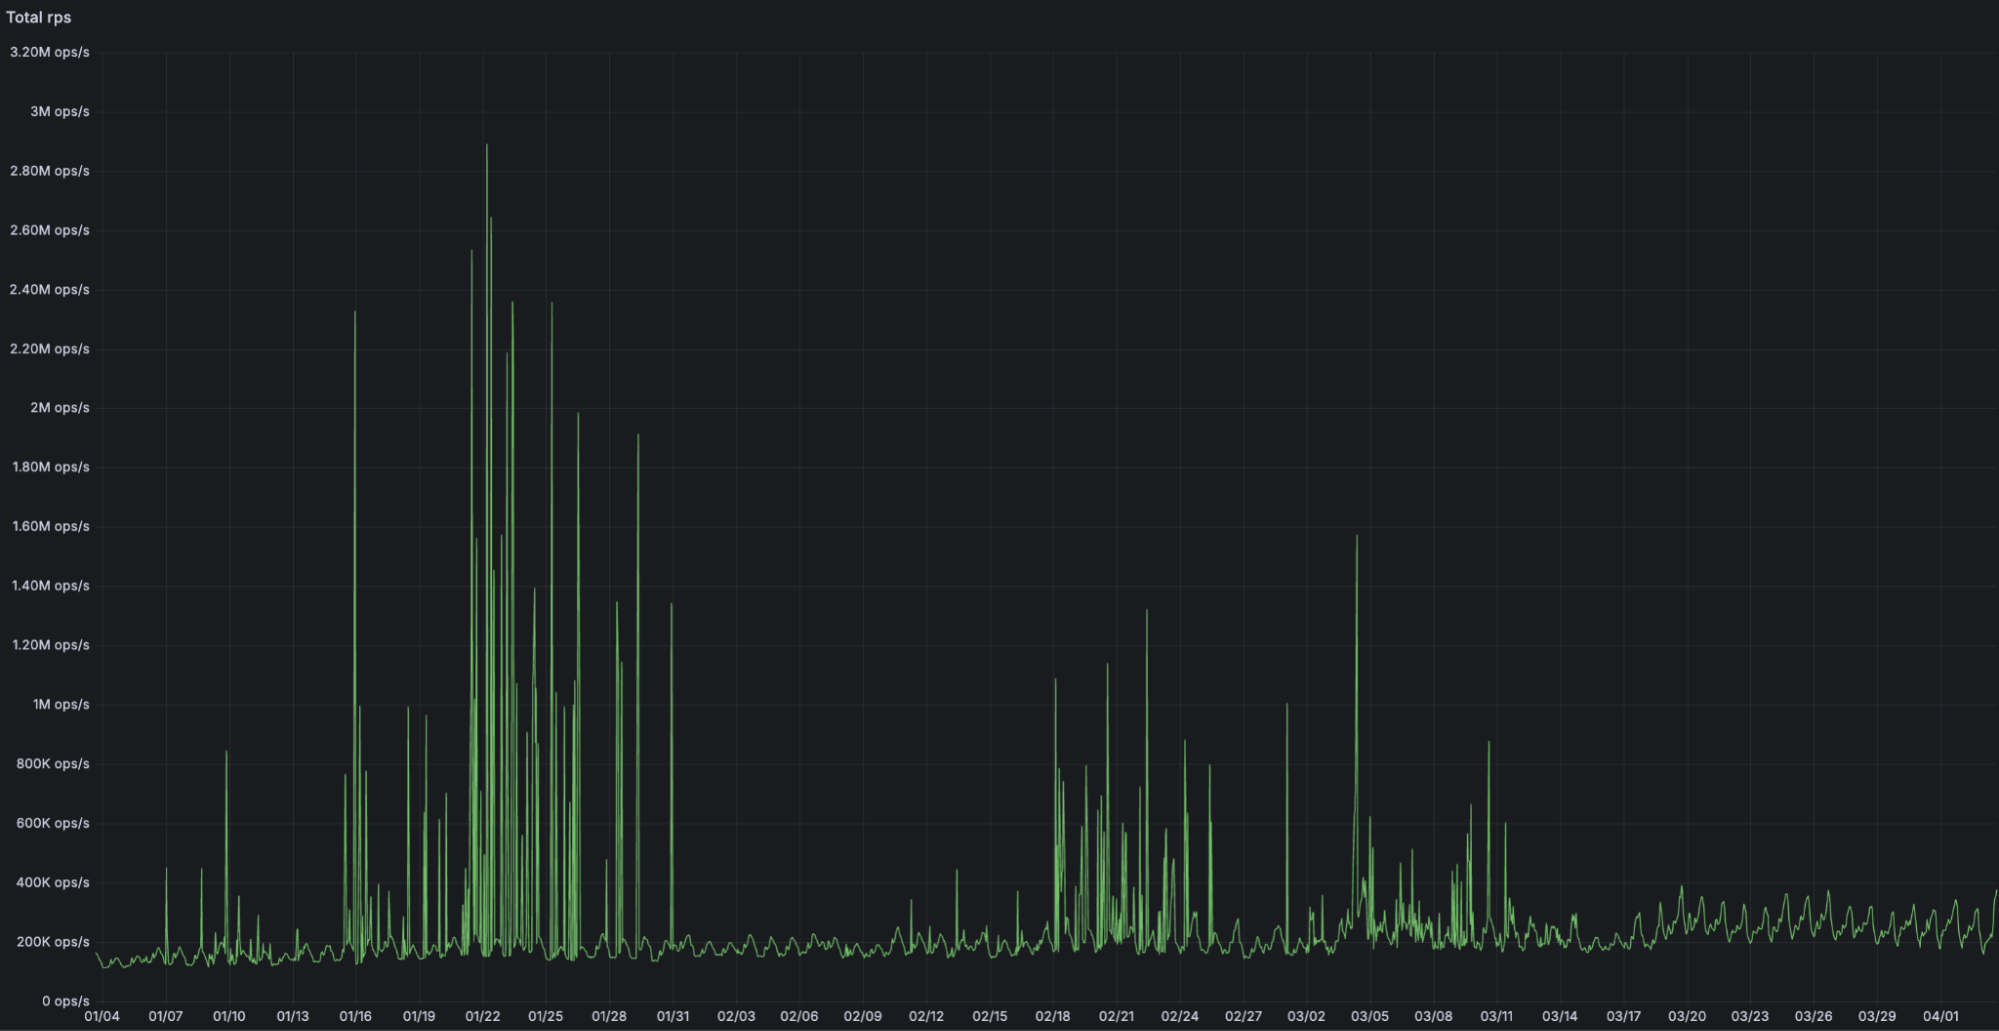
2024:7x traffic growth, processing 17,000 requests per second. Terraform support and production-grade backend were released.
2025:General Availability — Snippets introduces a new code editor, increased limits alongside other Cloudflare Rules products, integration with Trace, and a production-grade experience built for scale, handling over 2 million requests per second at peak. Integration with the Secrets Store is rolling out this summer.
New: Snippets + Trace
Cloudflare Trace now shows exactly which Snippets were triggered on a request. This makes it easier to debug traffic behavior, verify logic execution, and understand how your Snippets interact with other products in the request pipeline.
Whether you’re fine-tuning header logic or troubleshooting a routing issue, Trace gives you real-time insight into how your edge logic behaves in production.
Coming soon: Snippets + Secrets Store
In the third quarter, you’ll be able to securely access API keys, authentication tokens, and other sensitive values from Secrets Store directly in your Snippets. No more plaintext secrets in your code, no more workarounds.
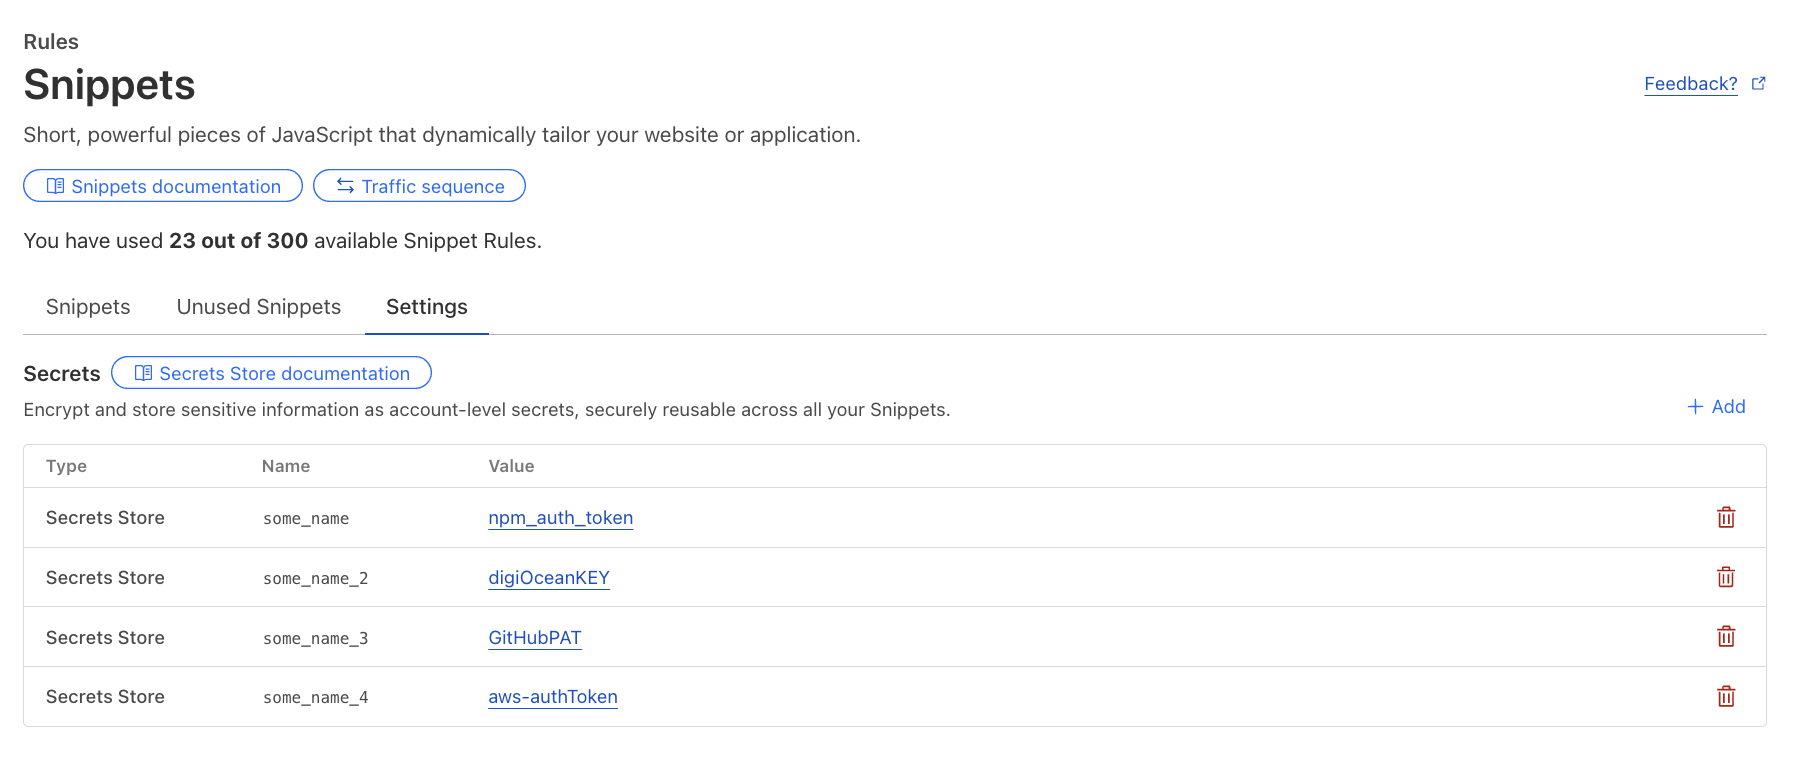
Once rolled out, secrets can be configured for Snippets via the dashboard or API under the new “Settings” button.
When to use Snippets vs. Cloudflare Workers
Snippets are fast, flexible, and free, but how do they compare to Cloudflare Workers? Both allow you to programmatically control traffic. However, they solve different problems:
Feature
Snippets
Workers
Execute scripts based on request attributes (headers, geolocation, cookies, etc.)
✅
❌
Modify HTTP requests/responses or serve a different response
✅
✅
Add, remove, or rewrite headers dynamically
✅
✅
Cache assets at the edge
✅
✅
Route traffic dynamically between origins
✅
✅
Authenticate requests, pre-sign URLs, run A/B testing
✅
✅
Perform compute-intensive tasks (e.g., AI inference, image processing)
❌
✅
Store persistent data (e.g., KV, Durable Objects, D1)
❌
✅
Deploy via CLI (Wrangler)
❌
✅
Use TypeScript, Python, Rust or other programming languages
❌
✅
Use Snippets when:
You need ultra-fast conditional traffic modifications directly on Cloudflare’s network.
You want to extend Cloudflare Rules beyond built-in actions.
You need free, unlimited invocations within the execution limits.
You are migrating from VCL, Akamai’s EdgeWorkers, or on-premise logic.
Use Workers when:
Your application requires state management, Developer Platform product integrations, or high compute limits.
You are building APIs, full-stack applications, or complex workflows.
You need logging, debugging tools, CLI support, and gradual rollouts.
Still unsure? Check out our detailed guide for best practices.
Snippets in action: real-world use cases
Below are practical use cases demonstrating Snippets. Each script can be dynamically triggered using our powerful Rules language, so you can granularly control which requests your Snippets will be applied to.
1. Dynamically modify headers
Inject custom headers, remove unnecessary ones, and tweak values on the fly:
export default {
  async fetch(request) {
    const timestamp = Date.now().toString(16); // convert timestamp to HEX
    const modifiedRequest = new Request(request, { headers: new Headers(request.headers) });
    modifiedRequest.headers.set("X-Hex-Timestamp", timestamp); // send HEX timestamp to upstream

    const response = await fetch(modifiedRequest);
    const newResponse = new Response(response.body, response); // make response from upstream immutable

    newResponse.headers.append("x-snippets-hello", "Hello from Cloudflare Snippets"); // add new response header
    newResponse.headers.delete("x-header-to-delete"); // delete response header
    newResponse.headers.set("x-header-to-change", "NewValue"); // replace the value of existing response header

    return newResponse;
  },
};
2. Serve a custom maintenance page
Route traffic to a maintenance page when your origin is undergoing planned maintenance:
export default {
    async fetch(request) { // for all matching requests, return predefined HTML response with 503 status code
        return new Response(`
            <!DOCTYPE html>
            <html lang="en">
            <head>
                <meta charset="UTF-8">
                <title>We'll Be Right Back!</title>
                <style> body { font-family: Arial, sans-serif; text-align: center; padding: 20px; } </style>
            </head>
            <body>
                <h1>We'll Be Right Back!</h1>
                <p>Our site is undergoing maintenance. Check back soon!</p>
            </body>
            </html>
        `, { status: 503, headers: { "Content-Type": "text/html" } });
    }
};
3. Retry failed requests to a backup origin
Ensure reliability by automatically rerouting requests when your primary origin returns an unexpected response:
export default {
  async fetch(request) {
    const response = await fetch(request); // send original request to the origin

    if (!response.ok && !response.redirected) { // if response is not 200 OK or a redirect, send to another origin
      const newRequest = new Request(request); // clone the original request to construct a new request
      newRequest.headers.set("X-Rerouted", "1"); // add a header to identify a re-routed request at the new origin
      const url = new URL(request.url); // clone the original URL
      url.hostname = "backup.example.com"; // send request to a different origin / hostname
      return await fetch(url, newRequest); // serve response from the backup origin
    }

    return response; // otherwise, serve response from the primary origin
  },
};
4. Redirect users based on their location
Send visitors to region-specific sites for better localization:
export default {
    async fetch(request) {
        const country = request.cf.country; // identify visitor's country using request.cf property
        const redirectMap = { US: "https://example.com/us", EU: "https://example.com/eu" }; // define redirects for each country
        if (redirectMap[country]) return Response.redirect(redirectMap[country], 301); // redirect on match
        return fetch(request); // otherwise, proceed to upstream normally
    }
};
Getting started with Snippets
Snippets are available right now in the Cloudflare dashboard under Rules > Snippets:
Go to Rules → Snippets.
Use prebuilt templates or write your own JavaScript code.
Configure a flexible rule to trigger your Snippet.
Cloudflare Snippets are now generally available, bringing fast, cost-free, and intelligent HTTP traffic control to all paid plans.
With native integration into Cloudflare Rules and Terraform — and Secrets Store integration coming this summer — Snippets provide the most efficient way to manage advanced traffic logic at scale.
Explore Snippets in the Cloudflare Dashboard and start optimizing your traffic with lightweight, flexible rules that enhance performance and reduce complexity.
As the Internet has become enmeshed in our everyday lives, so has our need for speed. No one wants to wait when adding shoes to our shopping carts, or accessing corporate assets from across the globe. And as the Internet supports more and more of our critical infrastructure, speed becomes more than just a measure of how quickly we can place a takeout order. It becomes the connective tissue between the systems that keep us safe, healthy, and organized. Governments, financial institutions, healthcare ecosystems, transit — they increasingly rely on the Internet. This is why at Cloudflare, building the fastest network is our north star.
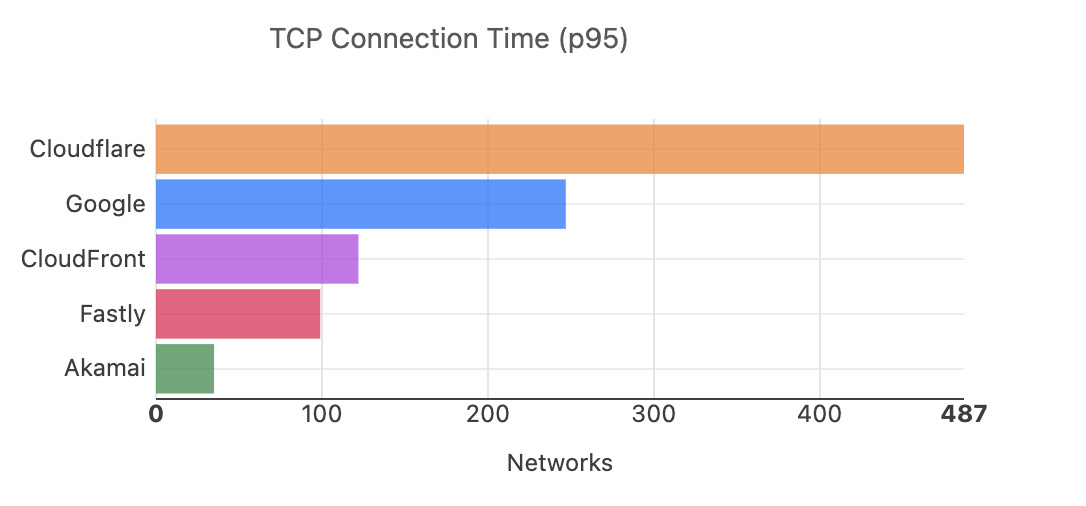
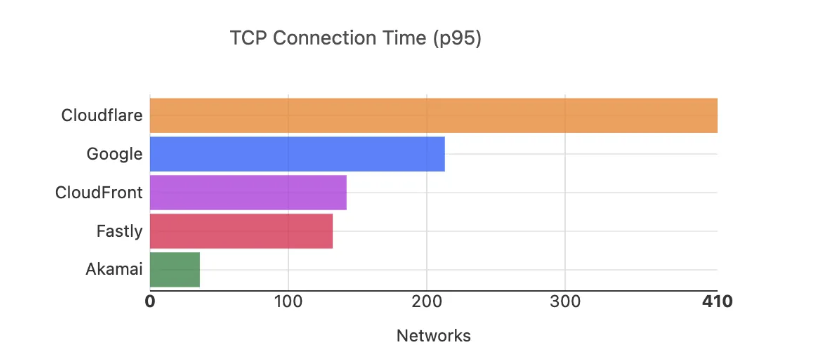
We’re happy to announce that we are the fastest network in 48% of the top 1000 networks by 95th percentile TCP connection time between November 2024, and March 2025, up from 44% in September 2024.
In this post, we’re going to share with you how our network performance has changed since our last post in September 2024, and talk about what makes us faster than other networks. But first, let’s talk a little bit about how we get this data.
How does Cloudflare get this data?
It’s happened to all of us — you casually click on a site, and suddenly you’ve reached a Cloudflare-branded error page. While you are shaking your fist at the sky, something interesting is happening on the back end. Cloudflare is using Real User Monitoring (RUM) to collect the data used to compare our performance against other networks. The monitoring we do is slightly different than the RUM Cloudflare offers to customers. When the error page loads, a 100 KB file is fetched and loaded. This file is hosted on networks like Cloudflare, Akamai, Amazon CloudFront, Fastly, and Google Cloud CDN. Your browser processes the performance data, and sends it to Cloudflare, where we use it to get a clear view of how these different networks stack up in terms of speed.
We’ve been collecting and refining this data since June 2021. You can read more about how we collect that data here, and we regularly track our performance during Innovation Weeks to hold ourselves accountable to you that we are always in pursuit of being the fastest network in the world.
How are we doing?
In order to evaluate Cloudflare’s speed relative to others, we measure performance across the top 1000 “eyeball” networks using the list provided by the Asia Pacific Network Information Centre (APNIC). So-called “eyeball” networks are those with a large concentration of subscribers/end users. This information is important, because it gives us signals for where we can expand our presence or peering, or optimize our traffic engineering. When benchmarking, we assess the 95th percentile TCP connection time. This is the time it takes a user to establish a TCP connection to the server they are trying to reach. This metric helps us illustrate how Cloudflare’s network makes your traffic faster by serving your customers as locally as possible.
When we look at Cloudflare’s performance across the top 1000 networks, we can see that we’re fastest in 487, or over 48%, of these networks, between November 2024 and March 2025:
In September 2024, we ranked #1 in 44% of these networks:
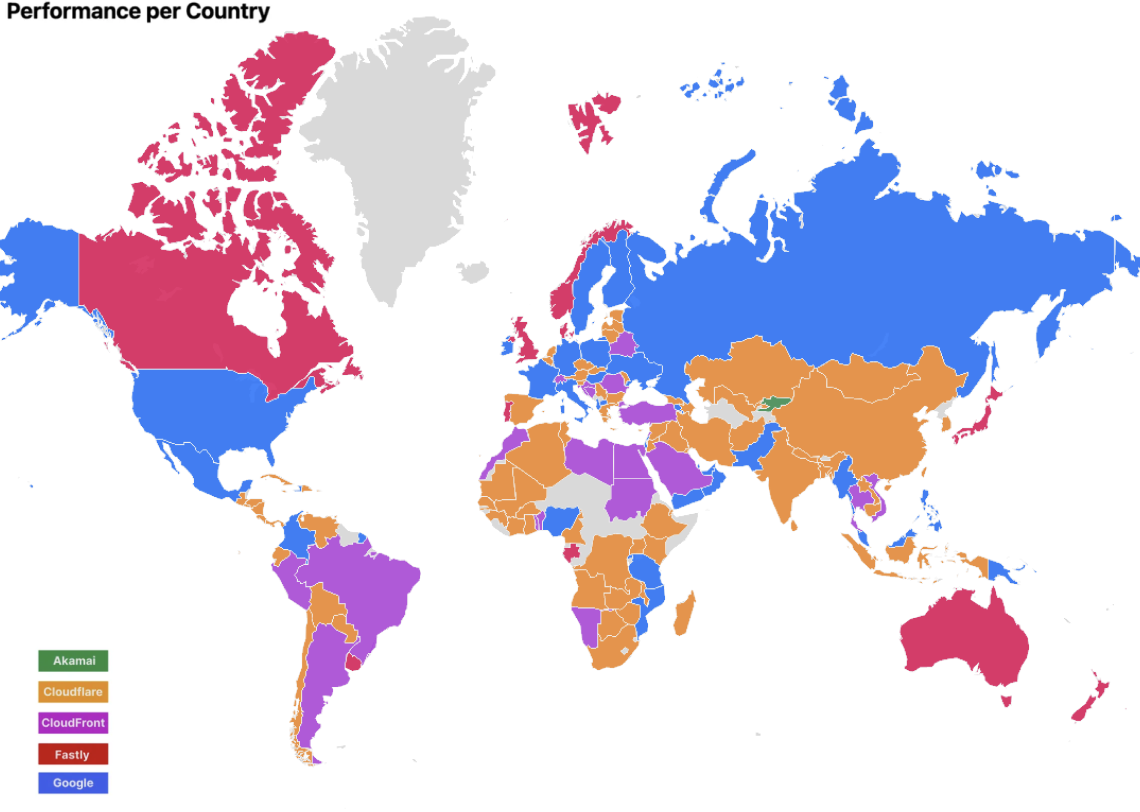
So why did we jump? To get a better understanding of why, let’s take a look at the countries where we improved, which will give us a better sense of where to dive in. This is what our network map looked like in September 2024 (grey countries mean we do not have enough data or users to derive insights):
(September 2024)
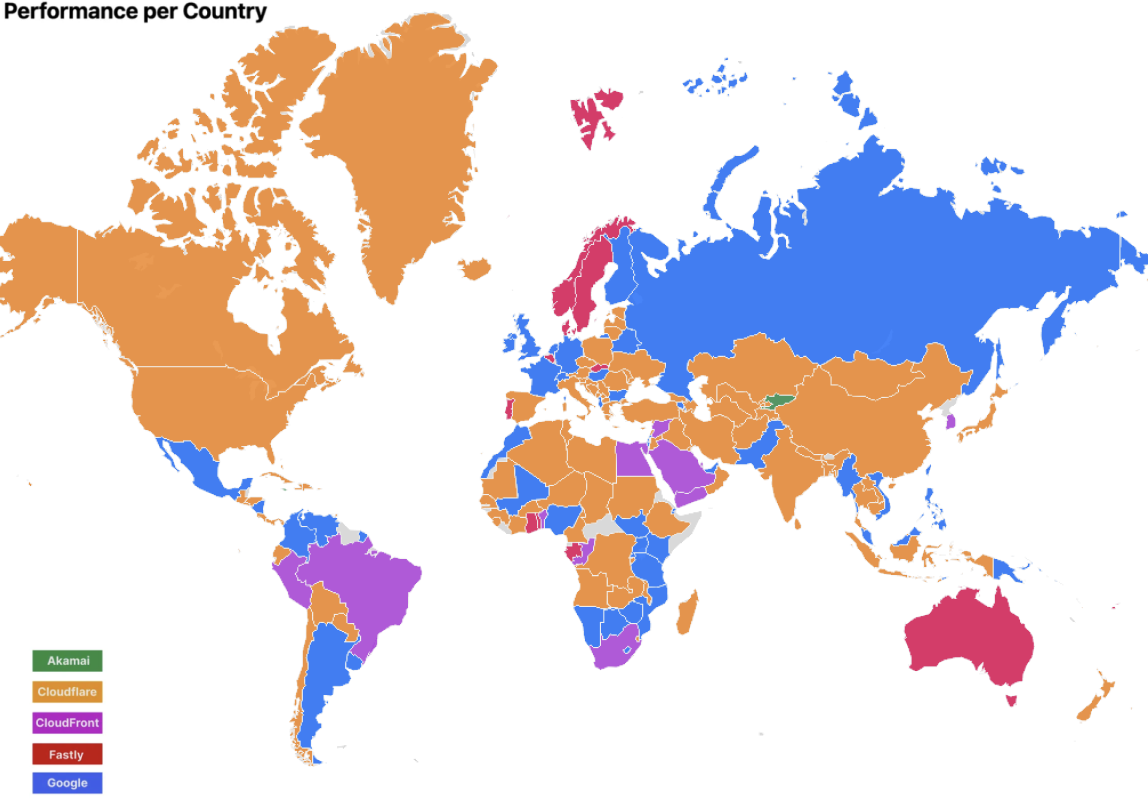
Today, using those same 95th percentile TCP connect times, we rank #1 in 48% of networks and the network map looks like this:
(March 2025)
We made most of our gains in Africa, where countries that previously didn’t have enough samples saw an increase in samples, and Cloudflare pulled ahead. This could mean that there was either an increase in Cloudflare users, or an increase in error pages shown. These countries got faster almost exclusively due to the presence of our Edge Partner deployments, which are Cloudflare locations embedded in last mile networks. In next-generation markets like many African countries, these locations are crucial towards being faster as connectivity to end users tends to fall back to places like South Africa or London if in-country peering does not exist.
But let’s take a look at a couple of other places and see why we got faster.
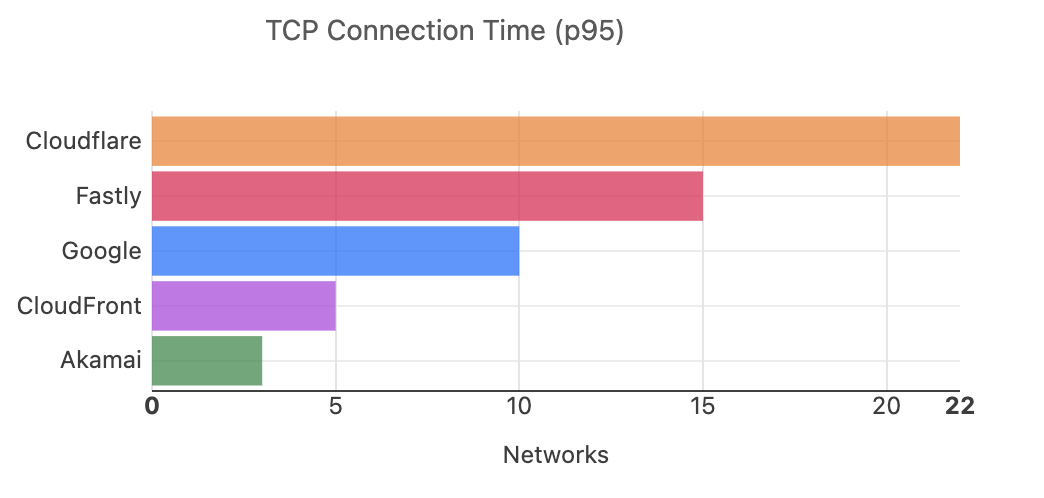
In Canada, we were not the fastest in September 2024, but we are the fastest today. Today, we are the fastest in 40% of networks, which is the most out of all of our competitors:
But when you look at the overall country numbers, we see that the race for the fastest network is quite close:
Canada 95th Percentile TCP Connect Time by Provider
Rank
Entity
Connect Time (P95)
#1 Diff
1
Cloudflare
179 ms
–
2
Fastly
180 ms
+0.48% (+0.87 ms)
3
Google
180 ms
+0.74% (+1.32 ms)
4
CloudFront
182 ms
+1.74% (+3.11 ms)
5
Akamai
215 ms
+20% (+36 ms)
The difference between Cloudflare and the third-fastest network is a little over a millisecond! As we’ve pointed out previously, such fluctuations are quite common, especially at higher percentiles. But there is still a significant difference between us and the slowest network; we’re around 20% faster.
However, looking at a place like Japan where were not the fastest in September 2024 but are now the fastest, there is a significant difference between Cloudflare and the number two network:
Japan 95th Percentile TCP Connect Time by Provider
Rank
Entity
Connect Time (P95)
#1 Diff
1
Cloudflare
116 ms
–
2
Fastly
122 ms
+5.23% (+6.08 ms)
3
Google
124 ms
+6.21% (+7.22 ms)
4
CloudFront
127 ms
+8.91% (+10 ms)
5
Akamai
153 ms
+32% (+37 ms)
Why is this? We are in more locations in Japan than our competitors and added more Edge Partner deployments in these locations, bringing us even closer to end-users. Edge Partner deployments are collaborations with ISPs, where we take space in their data centers, and peer with them directly.
Why?
Why do we track our network performance like this? The answer is simple: to improve user experience. This data allows us to track a key performance metric for Cloudflare and the other networks. When we see that we’re lagging in a region, it serves as a signal to dig deeper into our network.
This data is a gold mine for the teams tasked with improving Cloudflare’s network. When there are countries where Cloudflare is behind, it gives us signals for where we should expand or investigate. If we’re slow, we may need to invest in additional peering. If a region we have invested in heavily is slower, we may need to investigate our hardware. The example from Japan shows exactly how this can benefit: we took a location where we were previously on par with our competitors, added peering in new locations, and we pulled ahead.
On top of this map, we have autonomous system (ASN) level granularity on how we are performing on each one of the top 1000 eyeball networks, and we continuously optimize our traffic flow with each of them. This allows us to track individual networks that may lag and improve the customer experience in those networks through turning up peering, or even adding new deployments in those regions.
What’s next?
We’re sharing our updates on our journey to become #1 everywhere so that you can see what goes into running the fastest network in the world. From here, our plan is the same as always: identify where we’re slower, fix it, and then tell you how we’ve gotten faster.
We’re excited to announce Workers Observability – a new section in the Cloudflare Dashboard that allows you to query detailed log events across all Workers in your account to extract deeper insights.
In 2024, we set out to build the best first-party observability for any cloud platform. Since then, we’ve improved metrics reporting for all resources, launched Workers Logs to automatically ingest and store logs for Workers, and rebuilt real-time logs with improved filtering. However, observability insights have been limited to a single Worker.
Starting today, you can use Workers Observability to understand what is happening across all of your Workers:
Workers Metrics Dashboard (Beta): A single dashboard to view metrics and logs from all of your Workers
Query Builder (Beta): Construct structured queries to explore your logs, extract metrics from logs, create graphical and tabular visualizations, and save queries for faster future investigations.
Workers Logs: Now Generally Available, with a public API and improved invocation-based grouping.
Building queries
The Query Builder allows you to interact with your logs, and answer the “why” to any question you have. You can find it by navigating to Workers & Pages > Observability in the dashboard.
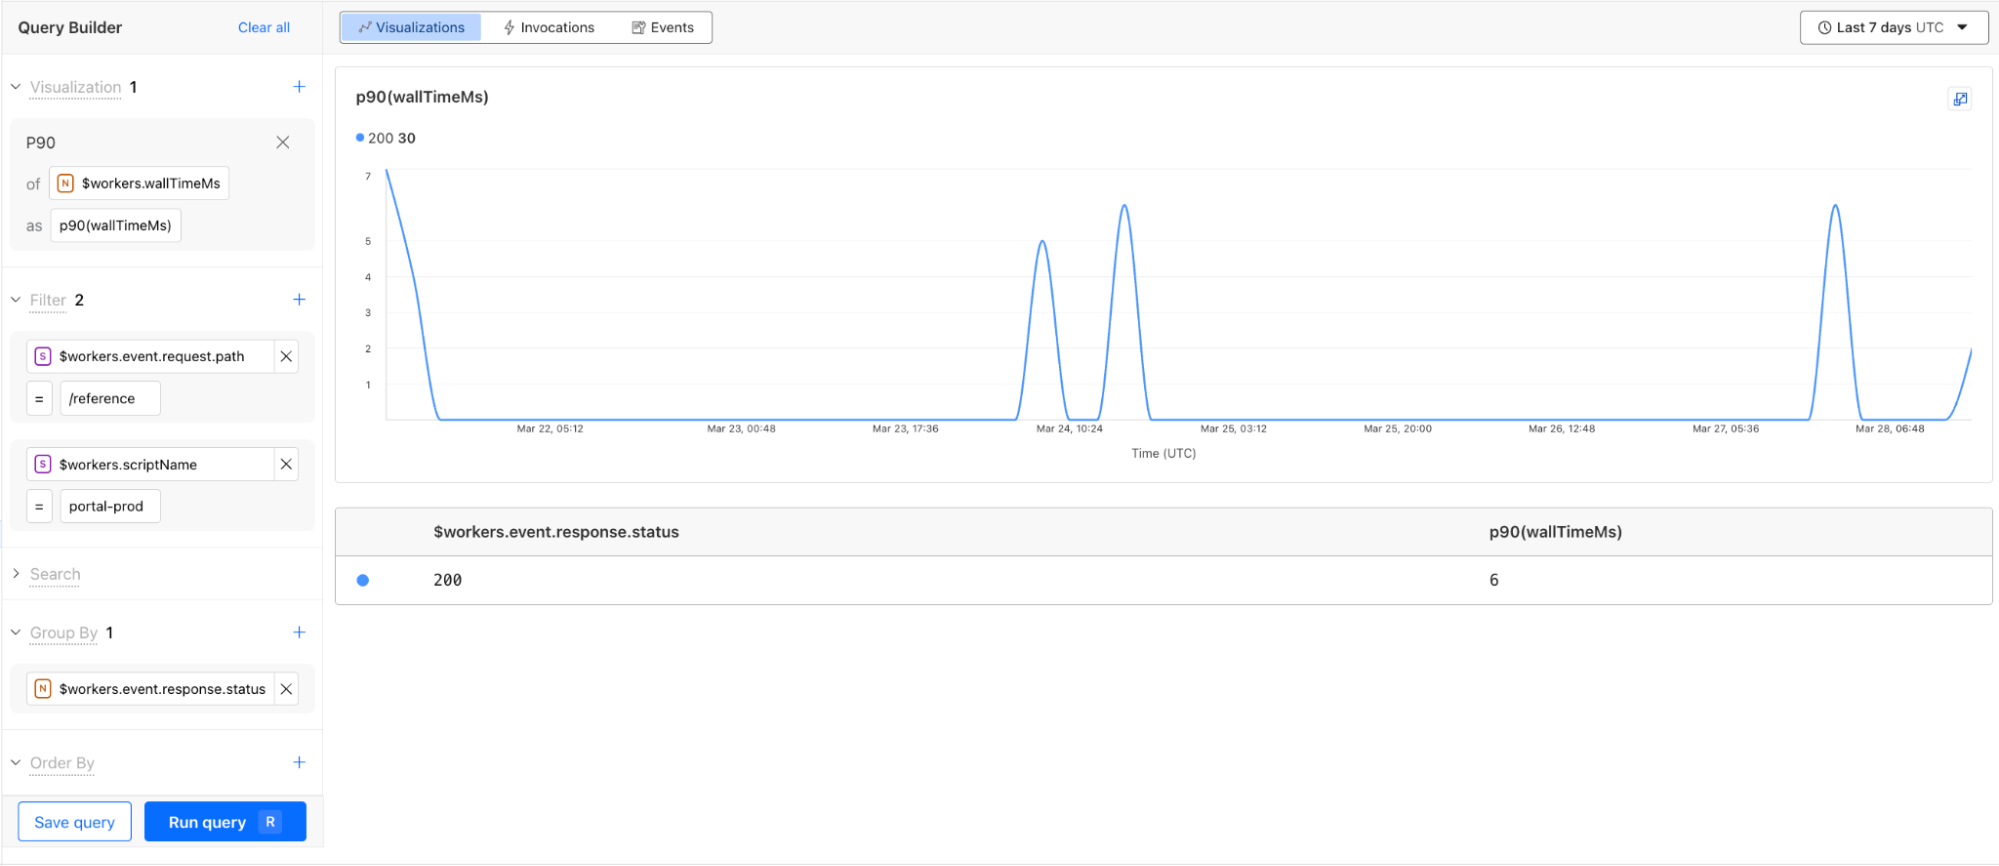
Using the Query Builder, you can now answer more questions than ever. For example, this query shows the p90 wall time for 200 OK responses from the /reference endpoint is 6 milliseconds.
The key components to structuring a query in the Query Builder are:
Visualizations: An aggregate function like average, count, percentile, or unique that performs a calculation on a group of values to return a single value. Each aggregate function returns a graph visualization and a summary table.
Filters: A condition that allows you to exclude data not matching the criteria.
Search: A condition that only returns the data matching the specified string.
Group by: A function to collapse a field into only its distinct values, allowing you to more granularly apply aggregate functions.
Order by: A sorting function to order the returned rows.
Limits: A cap on the number of returned rows, allowing you to focus on what is important.
The Query Builder relies on structured logs for efficient indexed queries and extracting metrics from logs. Workers Observability natively supports and encourages structured logs. Structured logs store context-rich metadata as key-value pairs in the form of distinct fields (high dimensionality), each with many potential unique values (high cardinality). Invocation Logs, which can be enabled in your Worker, contain deep insights from Cloudflare’s network, and are a great example of a structured log. By logging important metadata as a structured log, you empower yourself to answer questions about your system that you couldn’t predict when writing the code.
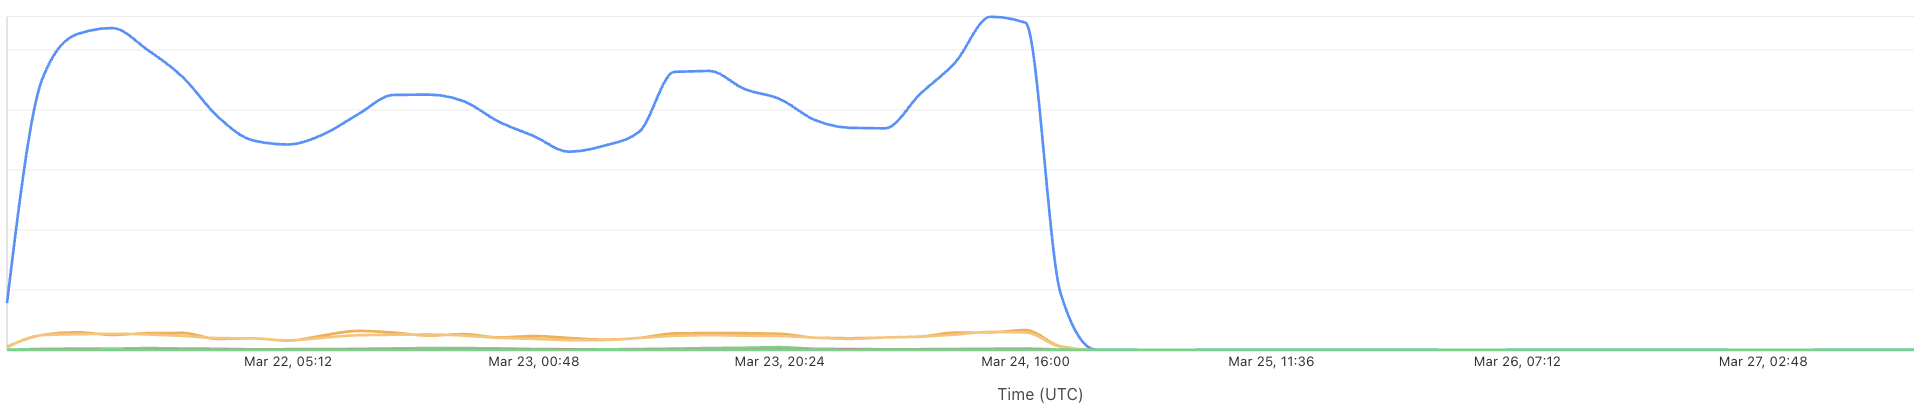
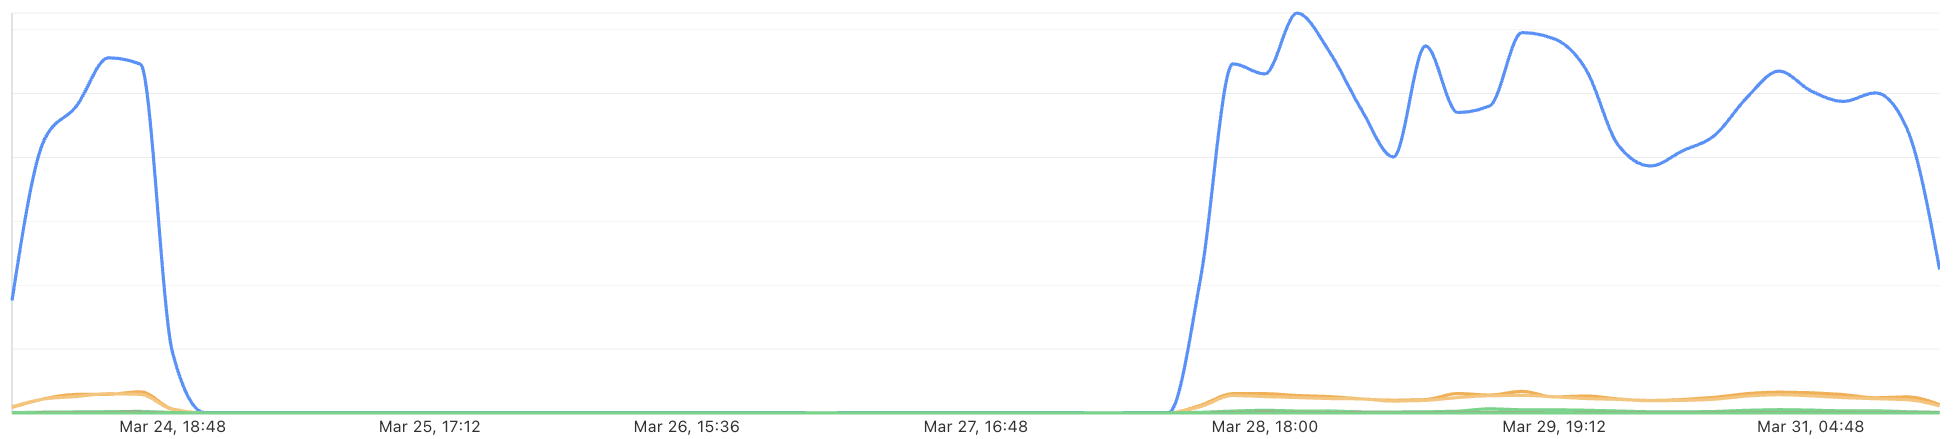
Internally at Cloudflare, we’ve already found tremendous value from this new product. During development, the Workers Observability team was able to use the Query Builder to discover a bug in the Workers Observability team’s staging environment. A query on the number of the events per script returned the following response:
After mapping this drop in recorded events against recent staging deployments, the team was able to isolate and root cause the introduction of the bug. Along with fixing the bug, the team also introduced new staging alerts to prevent errors like this from going unnoticed.
Queries built with the Query Builder or Workers Logs can be saved with a custom name and description. You can star your favorite queries, and also share them with your teammates using a shareable link, making it easier than ever to debug together and invest in developing visualizations from your telemetry data.
CPU time and wall time
You can now monitor CPU time and wall time for every Workers invocation across all of our observability offerings, including Tail Workers, Workers Logpush, and Workers Logs. These metrics help show how much time is spent executing code compared to the total elapsed time for the invocation, including I/O time.
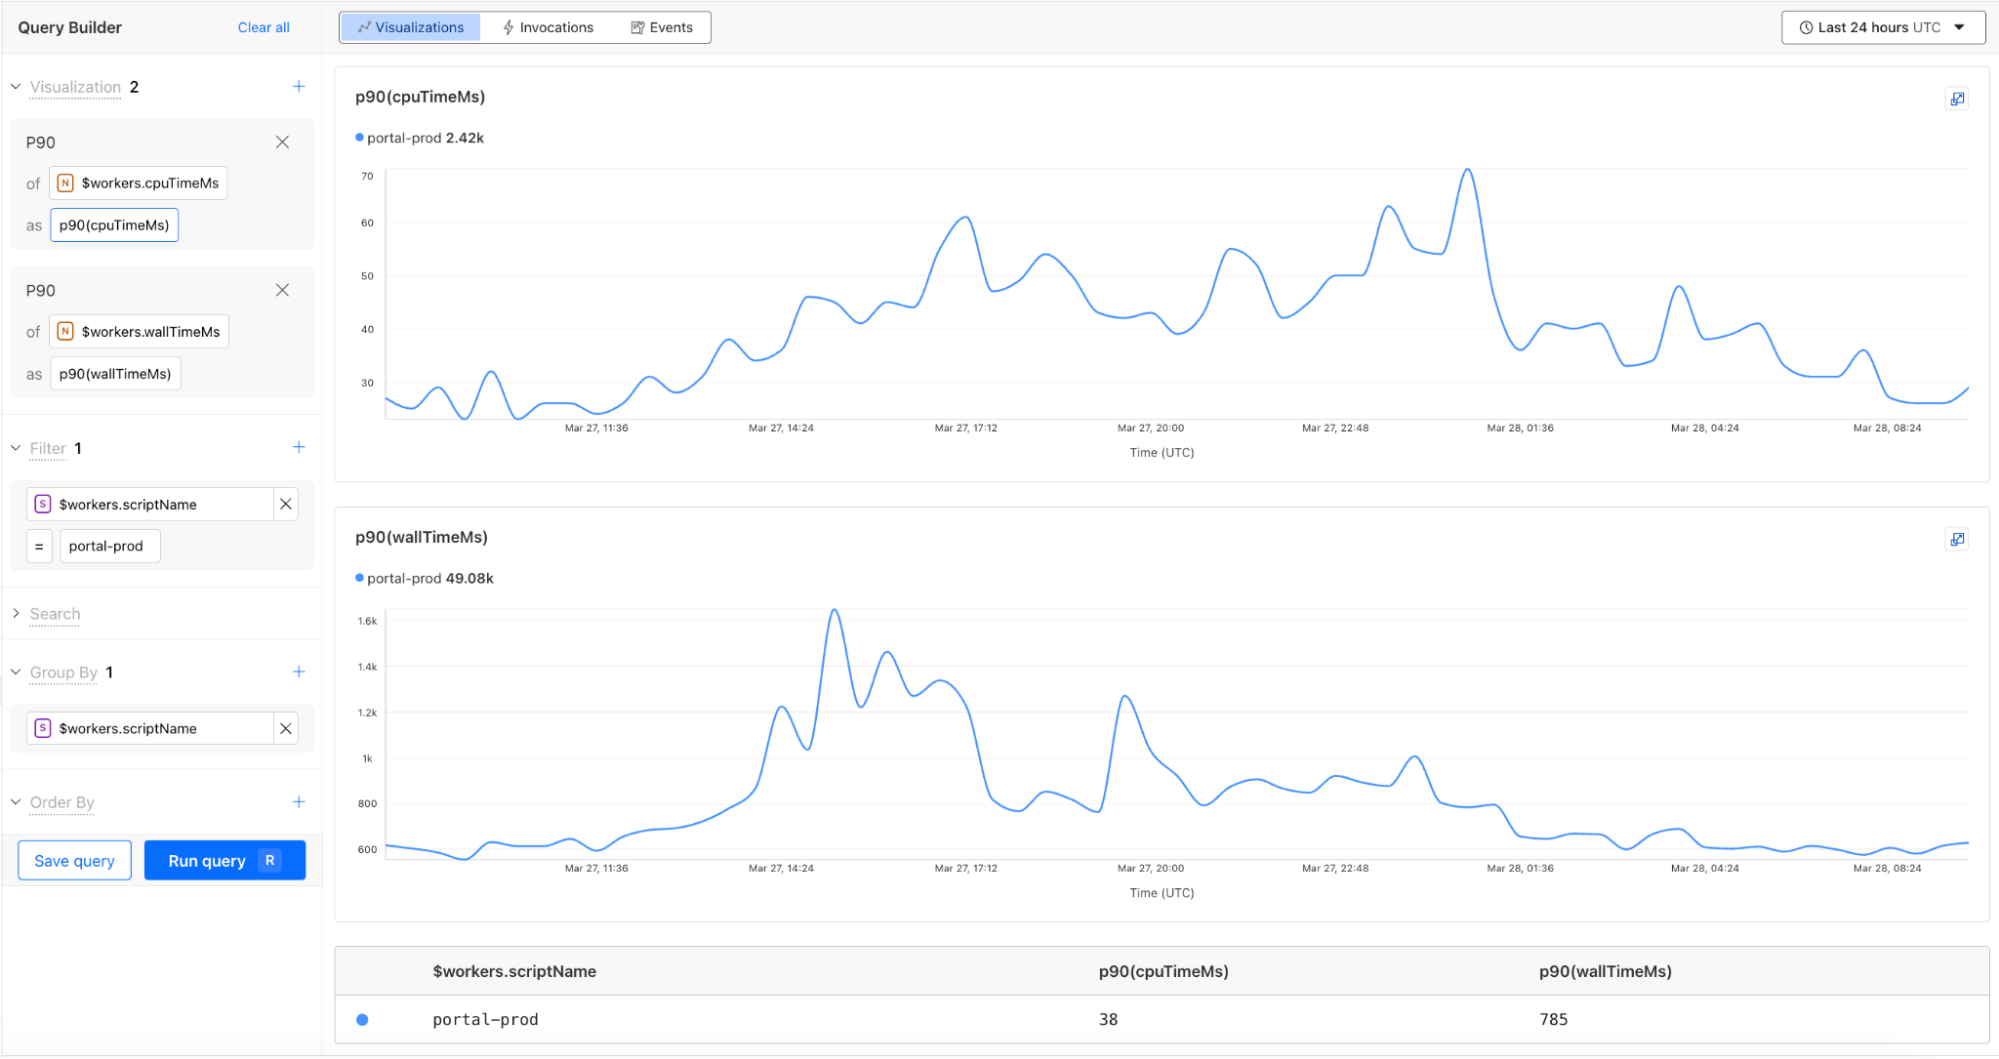
For example, using the CPU time and wall time surfaced in the Invocation Log, you can use the Query Builder to show the p90 CPU time and wall time traffic for a single Worker script.
Revamped Workers metrics
In February, we released a new view into your Workers’ metrics to help you monitor your gradual deployments with improved visualizations. Today, we are also launching a new Workers Metrics overview page in the Observability tab. Now you can easily compare metrics across Workers and understand the current state of your deployments, all from a single view.
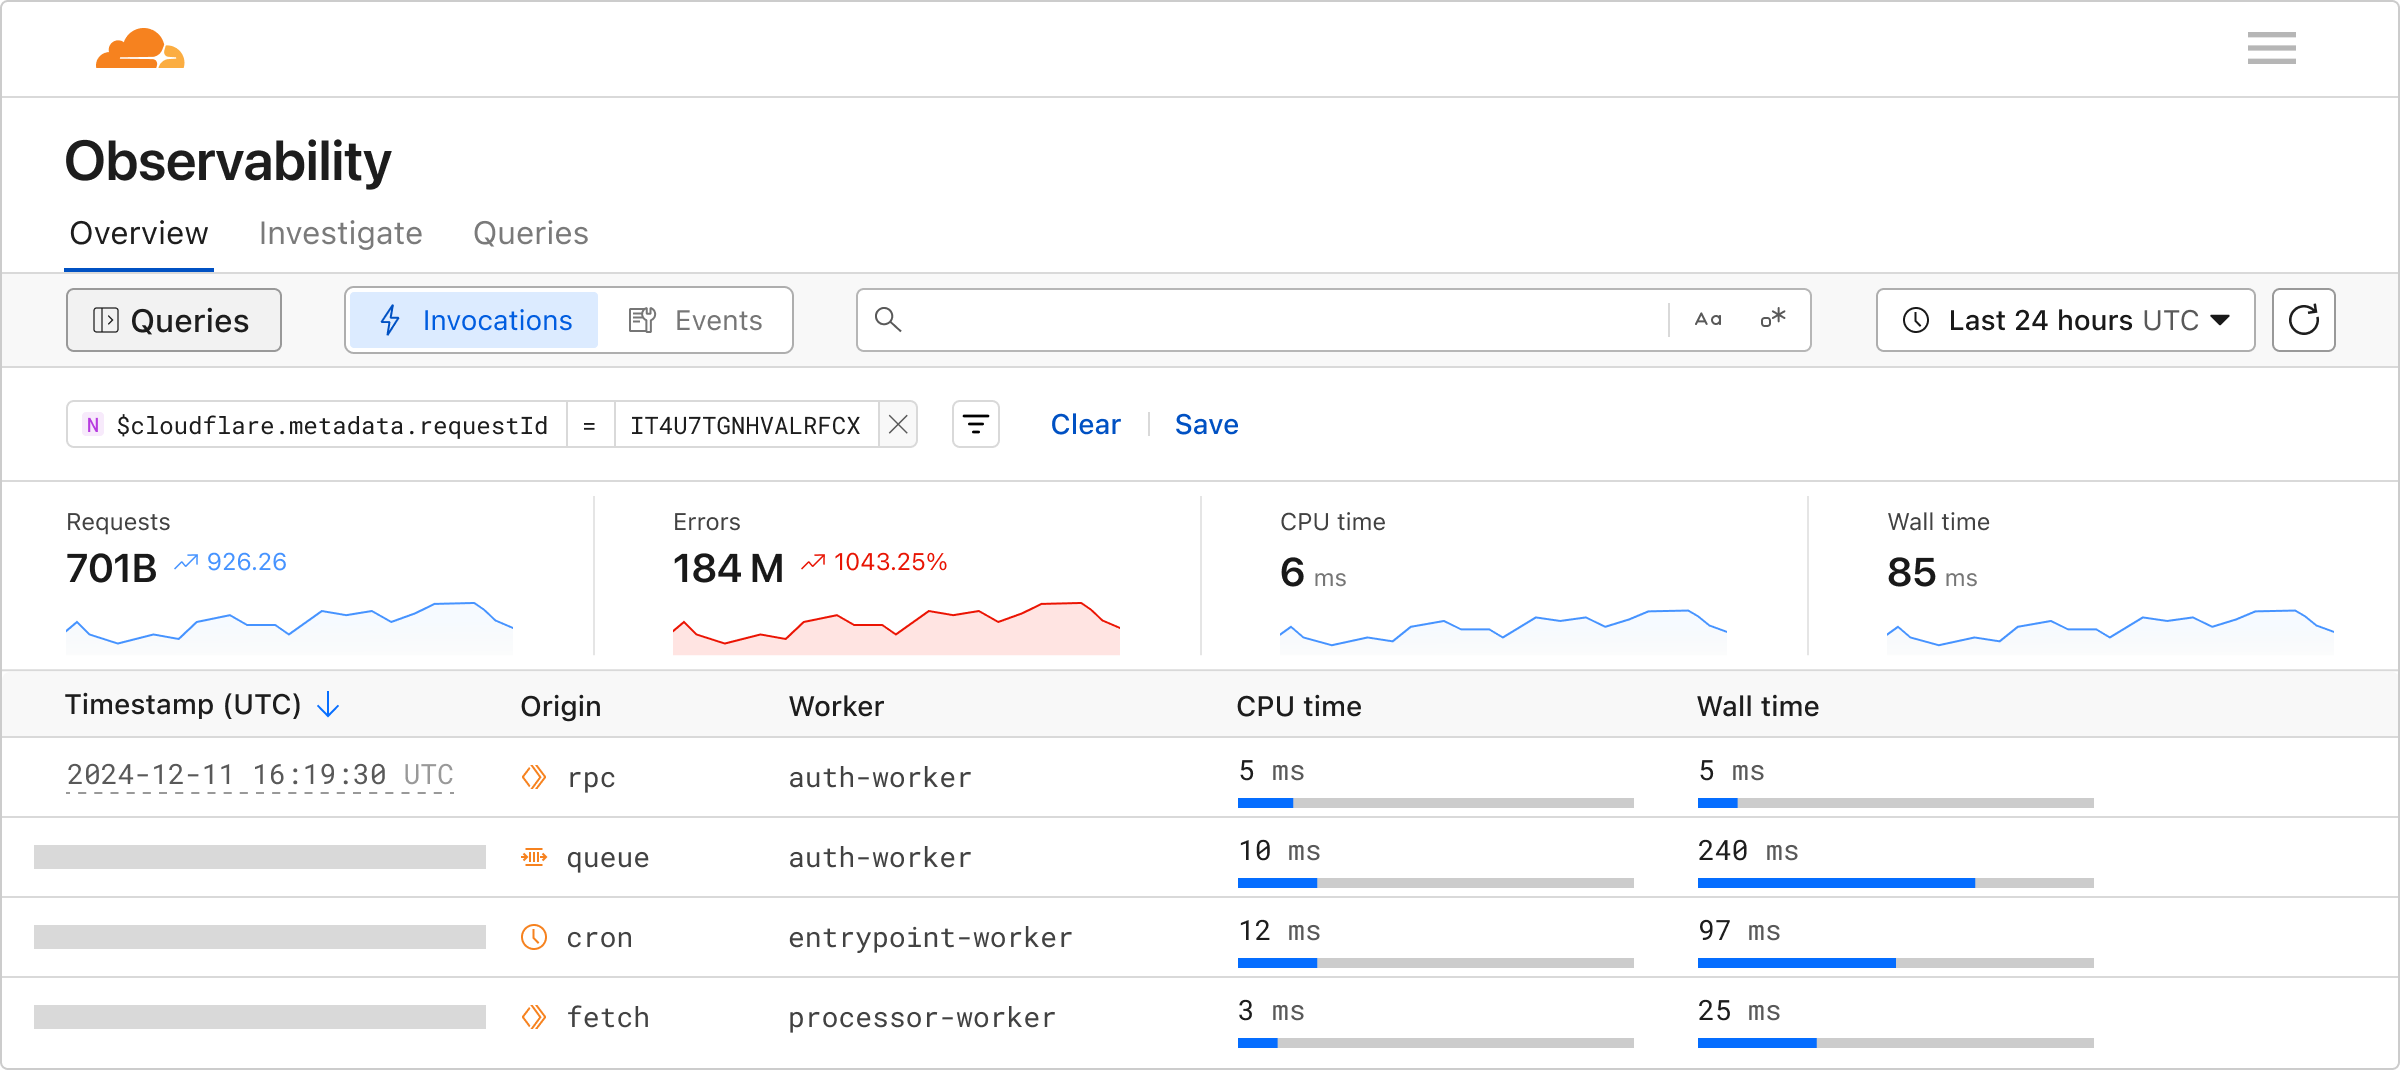
Invocations view
Invocations are mechanisms to trigger the execution of a Worker or Durable Object in response to an event, such as an alarm, cron job, or a fetch.
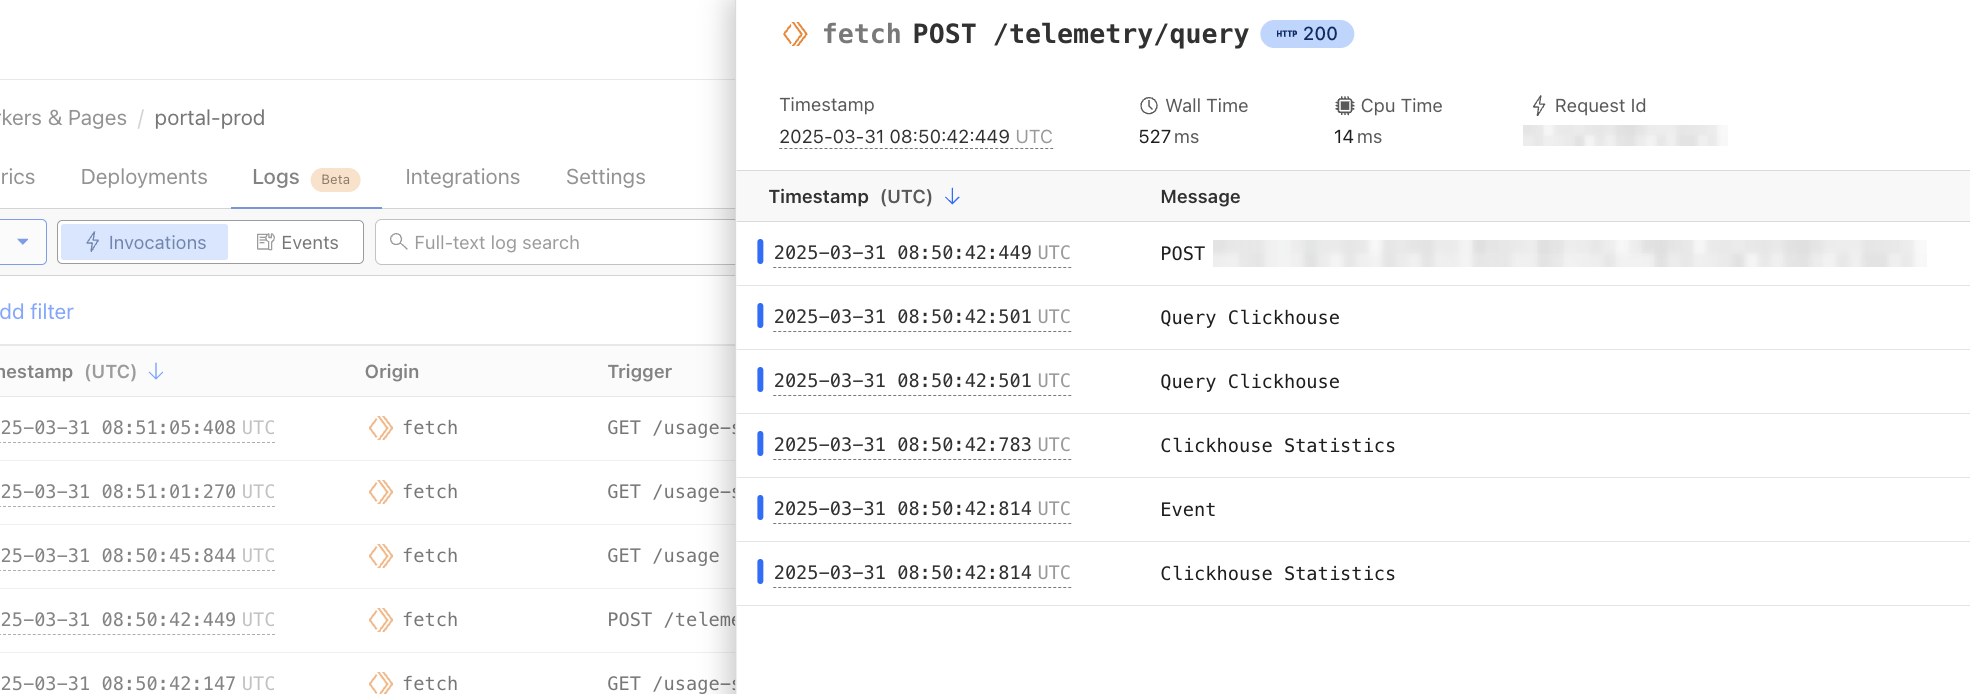
When the Worker or Durable Object executes, log events are emitted. To date, we have surfaced logs in an events view where each log is ordered by the time it was published.
We’re now introducing an Invocations View, so you can group and view all logs from each invocation. These views are available in each Worker’s view and the Workers Observability tab.
Workers Observability API
You can now use the Workers Observability API to programmatically retrieve your telemetry data and populate the tool of your choice.
The API allows you to automate, integrate, and customize in ways that our dashboard may not. For example, you may want to analyze your logs in a notebook or correlate your Workers logs with logs from a different source. Leveraging the Workers Observability API can help you optimize your monitoring strategy, automate repetitive tasks, and improve flexibility in how you interact with your telemetry data.
Enable Workers Logs today
To use Workers Logs, enable it in your Workers’ settings in the dashboard or add the following configuration to your Workers’ wrangler file:
We’re just getting started. We have lots in store to help make Cloudflare’s developer observability best-in-class. Join us in Discord in the #workers-observability channel for feedback and feature requests.
Tiered-memory systems feature multiple types of memory with varying
performance characteristics; on such systems, good performance depends on
keeping the most frequently used data in the fastest memory. Identifying
that data and placing it properly is a challenge that has kept developers
busy for years. Bharata Rao, presenting remotely during a
memory-management-track session at the 2025 Linux Storage, Filesystem,
Memory-Management, and BPF Summit, led a discussion on a potential solution he has recently
posted; Raghavendra K T was also named on the
session proposal. It seems likely, based on the discussion, that
developers working in this area will not run out of problems anytime soon.
The kernel
samepage merging (KSM) subsystem works by finding pages in memory with
the same contents, then replacing the duplicated copies with a single,
shared copy. KSM can improve memory utilization in a system, but has some
problems as well. In two memory-management-track sessions at the 2025
Linux Storage, Filesystem, Memory-Management, and BPF Summit, Mathieu
Desnoyers and Sourav Panda proposed improvements to KSM to
make it work better for specific use cases.
OpenSSH
10.0 has been released. Support for the DSA signature algorithm,
which was disabled by default beginning in 2015, has been
removed. Other notable changes include using the post-quantum algorithm mlkem768x25519-sha256
for key agreement by default, support for systemd-style socket
activation in Portable OpenSSH, and moving code for user
authentication from the sshd-session binary to the new ssh-auth binary:
Splitting this code into a separate binary ensures that the crucial
pre-authentication attack surface has an entirely disjoint address
space from the code used for the rest of the connection. It also
yields a small runtime memory saving as the authentication code will
be unloaded after the authentication phase completes. This change
should be largely invisible to users, though some log messages may now
come from “sshd-auth” instead of “sshd-session”. Downstream
distributors of OpenSSH will need to package the sshd-auth binary.
The release notes also warn that “software that naively matches
versions using patterns like “OpenSSH_1*”” may be confused by the
new version number.
Security updates have been issued by Debian (lemonldap-ng, libbssolv-perl, and phpmyadmin), Fedora (augeas, mariadb10.11, and thunderbird), Oracle (gimp, libxslt, python3.11, python3.12, tomcat, and xorg-x11-server), Red Hat (expat, grafana, opentelemetry-collector, and webkit2gtk3), SUSE (azure-cli-core, doomsday, kernel, and poppler), and Ubuntu (dotnet8, dotnet9, erlang, and poppler).
As the world of software development becomes increasingly global, the need for tools that support multiple languages has become paramount. Today, I am excited to announce expanded language support in Amazon Q Developer. In this post, I explore the recent expansion of language support in Amazon Q Developer, a powerful platform used by developers worldwide to discuss architecture, create documentation, design interfaces, and build applications.
While English remains the lingua franca of programming, the reality of modern software development extends far beyond code. Developers worldwide use Amazon Q Developer to discuss architecture decisions, create documentation, design user interfaces, and build applications that serve global audiences. By expanding language support, Amazon Q Developer now enables developers to have more natural, fluid conversations about complex technical concepts in their preferred language, whether they’re designing system architecture, generating documentation, or planning application localization strategies.
The power of this expanded language support is demonstrated in the following image, where I asked the same container hosting question in English, Chinese, Hindi, and Spanish. Not only does Amazon Q Developer now provide complete responses in these languages, but it also maintains technical accuracy while adapting to linguistic nuances. Furthermore, Q Developer now suggests follow-up questions and responses in the user’s chosen language, creating a more intuitive and seamless experience for developers worldwide. This natural flow of conversation in any language helps maintain the developer’s focus and flow, eliminating the mental overhead of constant translation.
Whether you’re a developer in Seoul writing documentation in Korean, a startup in Madrid brainstorming architecture in Spanish, or a team in Brazil collaborating in Portuguese, Amazon Q Developer is now ready to support your journey and your preferred language. Expanded language support is available to users of both the Free and Pro Tier starting today. Get started with Amazon Q Developer, and share your feedback. Together, we’re building a more inclusive and accessible future for software development.
This blog post authored by Elie Elmalem, Associate Scale Solutions Architect
When implementing event-driven architectures, customers frequently need to enrich their incoming events with additional information to make them more valuable for downstream consumers. Traditionally, customers using Amazon EventBridge would accomplish this by writing AWS Lambda functions to augment their events with supplementary data. However, this approach requires writing and maintaining custom code, adding complexity to their event processing pipeline.
Amazon EventBridge Pipes simplifies this process by providing a streamlined, managed service for event enrichment without the need to write and manage custom Lambda functions. This blog post demonstrates how you can use EventBridge Pipes’ built-in data enrichment capabilities to dynamically enhance your events with additional context and customer-specific details, making event processing more efficient and easier to maintain.
Amazon EventBridge Pipes
Amazon EventBridge creates a direct connection between sources and targets. Using an EventBridge bus helps you route and fan-out events to services in a pub/sub pattern. EventBridge Pipes on the other hand help you with point-to-point service integrations patterns. What sets it apart from the traditional event bus/rule pattern is its data transformation and enrichment support.
When defining an EventBridge Pipes, you specify the source and the target of the pipe. Pipes support a variety of sources and targets. Between the source and target, EventBridge Pipes supports filtering and enrichment. The filtering enables you to select and process a targeted subset of events. Enrichment allows you to enhance data by adding missing information before sending it to a target. For instance, if an event lacks necessary information, it ensures the target can properly consume the event. Enriching data can be very powerful, as it makes it possible to enhance a generic event and transform it. EventBridge Pipes support enrichment using Lambda functions, AWS Step Functions, Amazon API Gateway and EventBridge API destinations. More details about these concepts can be found in the Amazon EventBridge Pipes concepts documentation.
Figure 1: Representation of EventBridge Pipes showing filter and enrichment steps
This blog post will use the enrichment step of the pipe to create custom notifications.
Overview
To illustrate the functionality, this post uses a use case from a clothing retailer. Businesses such as this retailer want to keep their loyal customers engaged. Often, they rely on bulk promotional emails which lack personalization. In this use case, the retailer wants to send targeted promotion codes. As soon as the 10th order is placed, the code is sent via email or SMS to their customer.
Without EventBridge Pipes, this would be implemented using EventBridge to respond to the order event. All the events are sent to a custom Lambda function to process it. If the order meets the right conditions, the Lambda function sends a notification with the discount code to the customer using Amazon Simple Notification Service (Amazon SNS).
Figure 2: Traditional approach using EventBridge
While this architecture works, it requires you to maintain the integration code as well as the data enriching logic within the Lambda function as the function needs to extract the necessary information from the events and manage routing to SNS. As more microservices follow the same pattern, the code becomes more complex. This can lead to longer execution times along with higher cost and greater maintenance effort.
Simplifying using Amazon EventBridge Pipes
Amazon EventBridge Pipes can be used to simplify the previous implementation by handling the enrichment and integration between services. Amazon EventBridge Pipes take care of sending the event to your configured enrichment step and then routes the enriched event to the target. If the chosen method is a Lambda function, it leaves the function code to only focus on enrichment logic. It eliminates the need for code to extract the necessary fields from the event and to send notifications.
Figure 3: Solution architecture using EventBridge Pipes
As the event comes into the pipe, the enrichment step triggers a Lambda function, which will check eligibility and returns the message to route to SNS. If the customer is not eligible for a discount code, it returns an order confirmed message with the data retrieved from the original order event. If the customer is eligible for a discount, the message also contains the discount code.
The new message on the Orders queue triggers the EventBridge Pipes.
The pipe triggers an AWS Lambda function to enrich the data.
The functions checks if the customer is eligible for a discount code against an Amazon DynamoDB table. The table contains the number of times each customer has ordered.
The Lambda function returns the custom message that will be sent to the customer, either with or without the discount code.
The message is routed to an SNS topic by the EventBridge Pipe
Customer receives the notification via its preferred subscription method.
Building the updated flow
To build the updated flow, I have chosen to use the AWS Cloud Development Kit (CDK) in Python. You can use the code given here to deploy it into your account. The code can also be found on GitHub.
Note: This sample code is for testing purposes only and is not intended to be used in a production account.
For this solution, you need the following prerequisites:
An Identity and Access Management (IAM) role or user with enough permissions to create an IAM policy, DynamoDB table, SQS queue, SNS topic, Lambda Function and EventBridge Pipes.
The cdk init command creates a blog_code folder. The GitHub repository contains the code for the blog_code_stack.py file inside the blog_code folder.
Then, within the blog_code folder, create a new folder called lambda. Inside this new folder, create a file called index.py. This file will contain the code for the enrichment lambda function. Once again, this code can be found in the GitHub repository. Here is a section of the Lambda code:
def lambda_handler(event, context):

    message = json.loads(event[0]['body'])

    id = message['id']
    order_content = message['order_content']

    nmb_orders = get_number_of_orders(id)

    # Calculate orders left
    orders_left = MAX_ORDERS - nmb_orders

    # Update the DynamoDB table with the new number of orders
    if nmb_orders == MAX_ORDERS:
        update_table(id, 0)
    else:
        update_table(id, nmb_orders)

    if orders_left == 0:
        return [f"Thank you for your order of {order_content}. You have earned a 10% discount code on your next order: XA5GT2SF"]
    else:
        # Return the confirmation message
        return [f"Thank you for your order of {order_content}. This is your confirmation message! Only {orders_left} orders left until a 10% discount!"]
The Lambda function works in the following way:
It receives an event from the EventBridge Pipe which consists of the order and the ID of the user who made the order
It gets the number of orders that the user has already placed by calling a GetItem command on the DynamoDB table.
It calculates how many orders are left before the user gets the discount code.
It updates the DynamoDB table with the new number of orders to account for the one that was just placed.
If the user has placed the right number of orders, it returns a confirmation message with the discount code. Otherwise, it notifies the user of the number of orders that still need to be placed to get the discount.
Now, deploy the CDK stack into your account. Make sure that you are in the root directory of your project:
cdk bootstrap
cdk deploy
Once the stack has finished deploying, you will find an EventBridge pipe visible on the console by going to the EventBridge service page and clicking on Pipes in the left panel.
Testing the solution
To test the solution, you must first set up a subscription to the SNS topic to receive notifications. It is recommended to set up email notifications for simplicity and testing purposes. To do so, follow the instructions on the Amazon SNS documentation for the topic with name TargetTopic. When the subscription is set up, don’t forget to check your email inbox and confirm the subscription.
Once notifications are set up, visit the DynamoDB console page. You need to manually add an entry to the eligibility table to mimic a real environment:
Click on Tables in the left panel
Select the EligibilityTable table.
Click Explore table items then Create item
Enter an id with a value of 01.
Click Add new attribute and select String.
Under attribute name, enter orders, and under value enter 8.
Click Createitem.
The Items returned table should look like the following. This assumes that the customer has already place 8 orders.
Figure 4: Items returned table after adding a new item
Now, visit the SQS console page. You will need to send a message to the queue to mimic new orders being placed.
Click on the queue called SourceQueue.
Click Send and receive messages.
Under message body, paste in the following message and click Send message:
After a few minutes, you should receive an email confirming your order, as your order message is considered to be the 9th order. Send the message again to place a 10th order and you should receive your discount code!
Figure 5: Email received with a discount code
Cleanup
To delete the resources in your account, run the following command in the root directory of your project:
cdk destroy
Conclusion
This blog post showed how Amazon EventBridge Pipes and its enrichment feature can help you create tailored notifications. First, it discussed how it could be implemented using EventBridge and then presented a simplified implementation using EventBridge Pipes.
Today, we announce that the Pixtral Large 25.02 model is now available in Amazon Bedrock as a fully managed, serverless offering. AWS is the first major cloud provider to deliver Pixtral Large as a fully managed, serverless model.
Working with large foundation models (FMs) often requires significant infrastructure planning, specialized expertise, and ongoing optimization to handle the computational demands effectively. Many customers find themselves managing complex environments or making trade-offs between performance and cost when deploying these sophisticated models.
The Pixtral Large model, developed by Mistral AI, represents their first multimodal model that combines advanced vision capabilities with powerful language understanding. A 128K context window makes it ideal for complex visual reasoning tasks. The model delivers exceptional performance on key benchmarks including MathVista, DocVQA, and VQAv2, demonstrating its effectiveness across document analysis, chart interpretation, and natural image understanding.
One of the most powerful aspects of Pixtral Large is its multilingual capability. The model supports dozens of languages including English, French, German, Spanish, Italian, Chinese, Japanese, Korean, Portuguese, Dutch, and Polish, making it accessible to global teams and applications. It’s also trained on more than 80 programming languages including Python, Java, C, C++, JavaScript, Bash, Swift, and Fortran, providing robust code generation and interpretation capabilities.
Developers will appreciate the model’s agent-centric design with built-in function calling and JSON output formatting, which simplifies integration with existing systems. Its strong system prompt adherence improves reliability when working with Retrieval Augmented Generation (RAG) applications and large context scenarios.
With Pixtral Large in Amazon Bedrock, you can now access this advanced model without having to provision or manage any infrastructure. The serverless approach lets you scale usage based on actual demand without upfront commitments or capacity planning. You pay only for what you use, with no idle resources.
Cross-Region inference Pixtral Large is now available in Amazon Bedrock across multiple AWS Regions through cross-Region inference.
With Amazon Bedrock cross-Region inference, you can access a single FM across multiple geographic Regions while maintaining high availability and low latency for global applications. For example, when a model is deployed in both European and US Regions, you can access it through Region-specific API endpoints using distinct prefixes: eu.model-id for European Regions and us.model-id for US Regions . This approach enables Amazon Bedrock to route inference requests to the geographically closest endpoint, reducing latency while helping to meet regulatory compliance by keeping data processing within desired geographic boundaries. The system automatically handles traffic routing and load balancing across these Regional deployments, providing seamless scalability and redundancy without requiring you to keep track of individual Regions where the model is actually deployed.
See it in action As a developer advocate, I’m constantly exploring how our newest capabilities can solve real problems. Recently, I had a perfect opportunity to test the new multimodal capabilities in the Amazon Bedrock Converse API when my daughter asked for help with her physics exam preparation.
Last weekend, my kitchen table was covered with practice exams full of complex diagrams, force vectors, and equations. My daughter was struggling with conceptualizing how to approach these problems. That’s when I realized this was the perfect use case for the multimodal capabilities we’d just launched. I snapped photos of a particularly challenging problem sheet containing several graphs and mathematical notation, then used the Converse API to create a simple application that could analyze the images. Together, we uploaded the physics exam materials and asked the model to explain the solution approach.
What happened next impressed both of us—the model interpreted the diagrams, recognized the french language and the mathematical notation, and provided a step-by-step explanation of how to solve each problem. As we asked follow-up questions about specific concepts, the model maintained context across our entire conversation, creating a tutoring experience that felt remarkably natural.
# Effet Doppler avec une Source Sonore en Rotation

## Analyse du problème

Ce problème concerne l'effet Doppler produit par une source sonore en rotation. Une source émettant un son à 1500 Hz tourne sur une table tournante dans le sens antihoraire, et nous devons déterminer comment les fréquences sont perçues par un microphone fixe.

## Concepts clés

L'effet Doppler se produit lorsqu'il y a un mouvement relatif entre une source sonore et un observateur. La fréquence perçue dépend de si la source se rapproche ou s'éloigne de l'observateur.

La formule de l'effet Doppler est:
- Pour une source qui se rapproche: $f_{observée} = f_{source} \cdot \frac{v_{son}}{v_{son} - v_{source}}$
- Pour une source qui s'éloigne: $f_{observée} = f_{source} \cdot \frac{v_{son}}{v_{son} + v_{source}}$

## Solution étape par étape

### Étape 1: Analyser le mouvement de la source
La source tourne sur un cercle et le microphone est fixe à 40 cm du centre de rotation. Aux différentes positions (a, b, c), la source a des vitesses radiales différentes par rapport au microphone:

- Position a: La source se déplace perpendiculairement à la ligne source-microphone (vitesse radiale nulle)
- Position b: La source s'éloigne du microphone (vitesse radiale positive)
- Position c: La source se rapproche du microphone (vitesse radiale négative)

### Étape 2: Déterminer l'effet sur les fréquences perçues

- À la position a: Pas d'effet Doppler car la vitesse radiale est nulle, donc $f_a = f_{source} = 1500$ Hz
- À la position b: La source s'éloigne, donc $f_b < f_{source}$, donc $f_b < 1500$ Hz
- À la position c: La source se rapproche, donc $f_c > f_{source}$, donc $f_c > 1500$ Hz

### Étape 3: Comparer les fréquences

D'après notre analyse:
- $f_a = 1500$ Hz
- $f_b < 1500$ Hz
- $f_c > 1500$ Hz

Donc: $f_c > f_a > f_b$

## Conclusion

La proposition correcte est: $f_c > f_a > f_b$

Cette réponse correspond à la troisième proposition dans l'énoncé. Lorsque la source tourne, la fréquence perçue est plus élevée quand la source se rapproche (position c), égale à la fréquence émise quand la source se déplace perpendiculairement (position a), et plus basse quand la source s'éloigne (position b).
The model uses the language of the question to respond. After a thoughtful analysis, it says that the correct answer is f_c > f_a > f_b (and it is right!)
The beauty of this interaction was how seamlessly the Converse API handled the multimodal inputs. As a builder, I didn’t need to worry about the complexity of processing images alongside text—the API managed that complexity and returned structured responses that my simple application could present directly to my daughter.
Here is the code I wrote. I used the Swift programming language, just to show that Python is not the only option you have .
private let modelId = "us.mistral.pixtral-large-2502-v1:0"

// Define the system prompt that instructs Claude how to respond
let systemPrompt = """
You are a math and physics tutor. Your task is to:
1. Read and understand the math or physics problem in the image
2. Provide a clear, step-by-step solution to the problem
3. Briefly explain any relevant concepts used in solving the problem
4. Be precise and accurate in your calculations
5. Use mathematical notation when appropriate

Format your response with clear section headings and numbered steps.
"""
let system: BedrockRuntimeClientTypes.SystemContentBlock = .text(systemPrompt)

// Create the user message with text prompt and image
let userPrompt = "Please solve this math or physics problem. Show all steps and explain the concepts involved."
let prompt: BedrockRuntimeClientTypes.ContentBlock = .text(userPrompt)
let image: BedrockRuntimeClientTypes.ContentBlock = .image(.init(format: .jpeg, source: .bytes(finalImageData)))

// Create the user message with both text and image content
let userMessage = BedrockRuntimeClientTypes.Message(
    content: [prompt, image],
    role: .user
)

// Initialize the messages array with the user message
var messages: [BedrockRuntimeClientTypes.Message] = []
messages.append(userMessage)

// Configure the inference parameters
let inferenceConfig: BedrockRuntimeClientTypes.InferenceConfiguration = .init(maxTokens: 4096, temperature: 0.0)

// Create the input for the Converse API with streaming
let input = ConverseStreamInput(inferenceConfig: inferenceConfig, messages: messages, modelId: modelId, system: [system])

// Make the streaming request
do {
    // Process the stream
    let response = try await bedrockClient.converseStream(input: input)

    // Iterate through the stream events
    for try await event in stream {
        switch event {
        case .messagestart:
            print("AI-assistant started to stream")

        case let .contentblockdelta(deltaEvent):
            // Handle text content as it arrives
            if case let .text(text) = deltaEvent.delta {
                DispatchQueue.main.async {
                    self.streamedResponse += text
                }
            }

        case .messagestop:
            print("Stream ended")
            // Create a complete assistant message from the streamed response
            let assistantMessage = BedrockRuntimeClientTypes.Message(
                content: [.text(self.streamedResponse)],
                role: .assistant
            )
            messages.append(assistantMessage)

        default:
            break
        }
    }
And the result in the app is stunning.
By the time her exam rolled around, she felt confident and prepared—and I had a compelling real-world example of how our multimodal capabilities in Amazon Bedrock can create meaningful experiences for users.
Get started today The new model is available through these Regional API endpoints: US East (Ohio, N. Virginia), US West (Oregon), and Europe (Frankfurt, Ireland, Paris, Stockholm). This Regional availability helps you meet data residency requirements while minimizing latency.
This launch represents a significant step forward in making advanced multimodal AI accessible to developers and organizations of all sizes. By combining Mistral AI’s cutting-edge model with AWS serverless infrastructure, you can now focus on building innovative applications without worrying about the underlying complexity.
Visit the Amazon Bedrock console today to start experimenting with Pixtral Large 25.02 and discover how it can enhance your AI-powered applications.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.




 .
