Tag Archives: Amazon EC2

AWS Weekly Roundup: What’s Next with AWS 2026, Amazon Quick, OpenAI partnership, and more (May 4, 2026)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-whats-next-with-aws-2026-amazon-quick-openai-partnership-and-more-may-4-2026/

Last week, I took some time off in York, England, often described as the most haunted city in the country. I wandered through the ruins of abbeys that have stood for nearly a thousand years, walked along medieval walls, and spent an evening on a ghost tour hearing stories passed down through centuries. There’s something grounding about standing in a place that has witnessed so much history. Now I’m back at my desk, and the contrast is hard to miss: those abbey stones have stood for a thousand years largely unchanged, while in the span of a single week away, the pace of technological change has moved forward yet again.
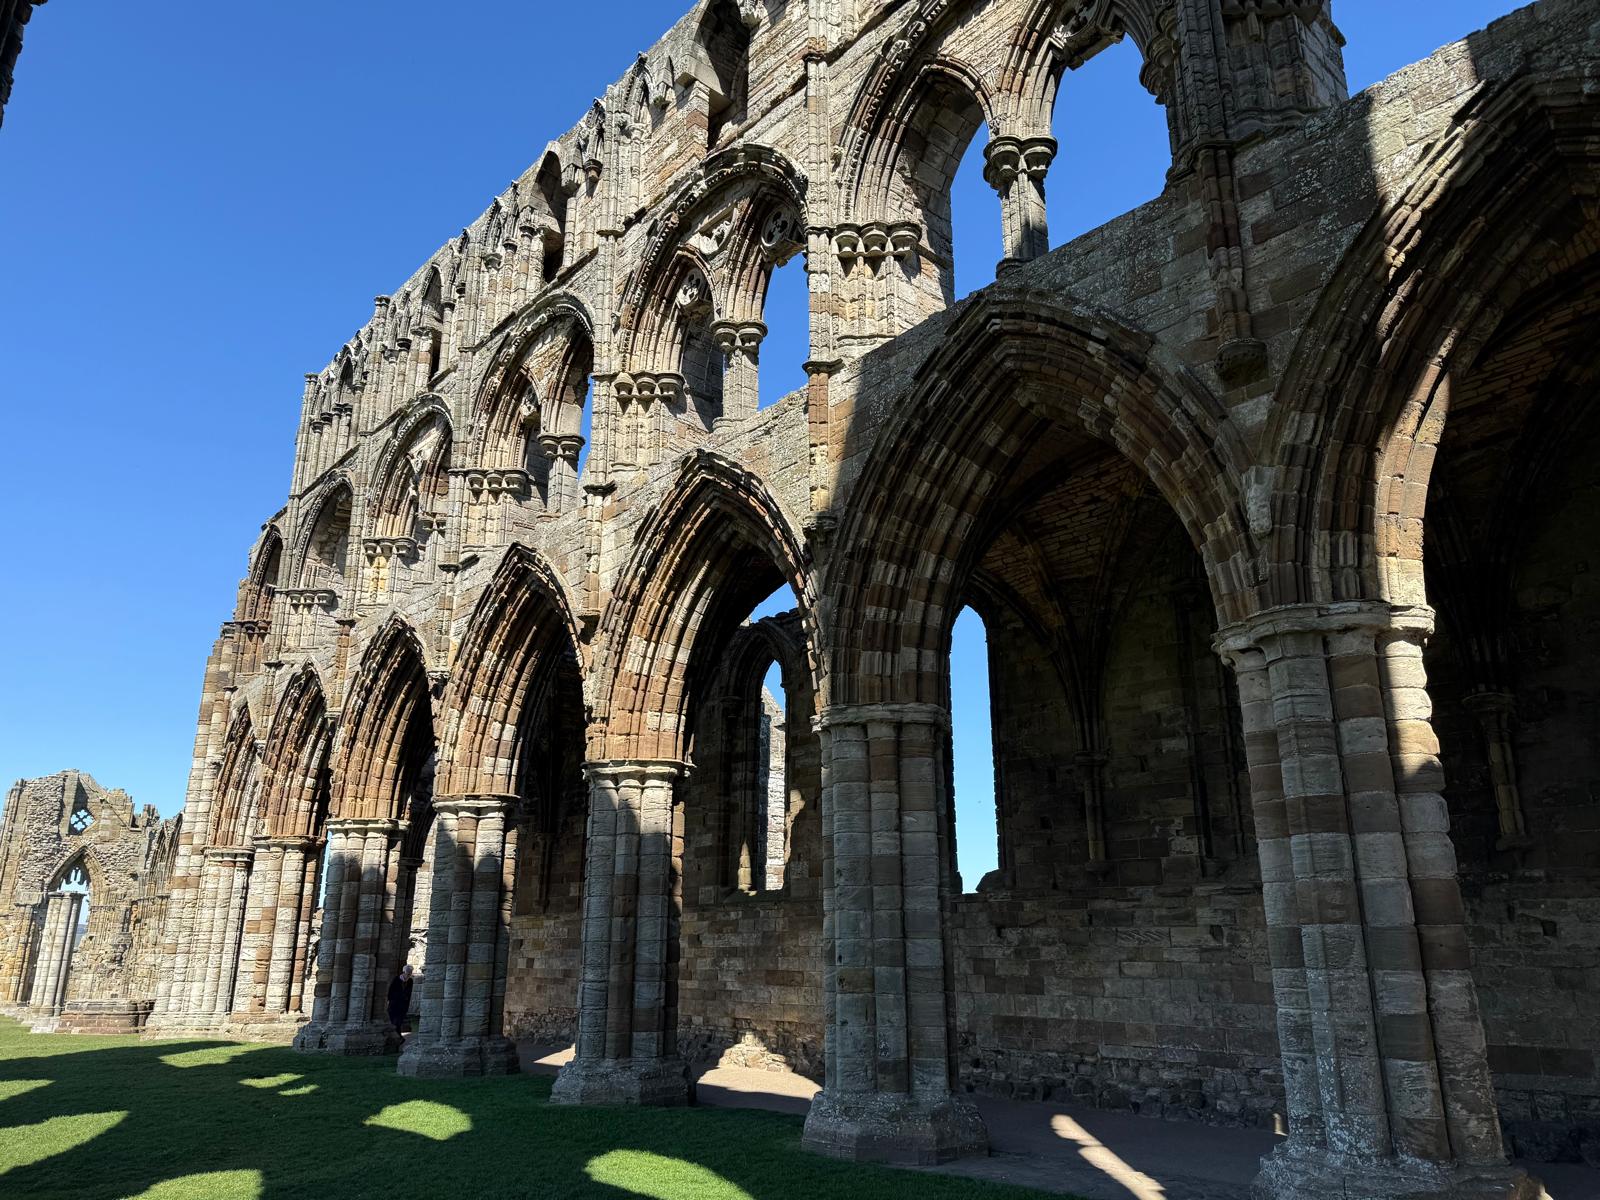
The ruins of Whitby Abbey in North Yorkshire. Stones that have seen a thousand years, while this week alone brought another wave of change.

Now, let’s get into this week’s AWS news.

Headlines
On April 28, Matt Garman, CEO of AWS, Colleen Aubrey, SVP Amazon Applied AI Solutions, Julia White, CMO of AWS, and OpenAI leaders took the stage to share how customers are changing the way businesses operate with agents. The event brought a packed slate of announcements across Amazon Quick, Amazon Connect, and a deeper partnership with OpenAI. Here’s a roundup of the biggest announcements from the event.

Amazon Quick expands with a desktop app, new pricing plans, and visual asset generation – Amazon Quick is an AI assistant for work that connects to your apps, learns what matters to you, and takes action on your behalf. This week, Quick introduced a new desktop app (Preview) that keeps you connected to your local files, calendar, and communications without opening a browser. You can sign up within minutes using your personal email address or existing Google, Apple, Github, or Amazon credentials—no AWS account required. Quick can now generate polished documents, presentations, infographics, and images directly from the chat interface, and native integrations expand to include Google Workspace, Zoom, Airtable, Dropbox, and Microsoft Teams. A new Build custom apps with Quick capability (Preview) lets you create intelligent apps, dashboards, and web pages connected to the rest of your business using natural language.

Amazon Connect expands into four agentic AI solutions – Amazon Connect is expanding from a single product into a set of four agentic AI solutions designed to work within your existing workflows. Amazon Connect Decisions is a supply chain planning and intelligence solution that shifts teams from crisis management to proactive planning, combining 30 years of Amazon operational science with more than 25 specialized supply chain tools. Amazon Connect Talent (Preview) is an agentic AI hiring solution that delivers AI-led interviews, science-backed assessments, and consistent evaluation for talent acquisition leaders managing scaled hiring. Amazon Connect Customer, previously known as Amazon Connect, delivers personalized customer experiences across voice, chat, and digital channels, with new configuration capabilities that enable organizations to set up conversational AI in weeks rather than months. Amazon Connect Health delivers agentic patient verification, appointment management, patient insights, ambient documentation, and medical coding, giving patients faster access to care and clinicians more time to deliver it.

AWS and OpenAI expand their partnership across Amazon Bedrock – AWS and OpenAI are bringing the latest OpenAI models to Amazon Bedrock, launching Codex on Amazon Bedrock, and introducing Amazon Bedrock Managed Agents powered by OpenAI — all in limited preview. OpenAI models on Amazon Bedrock (Limited preview) brings the latest OpenAI models, including GPT-5.5 and GPT-5.4, to the Bedrock APIs you already use, with unified security, governance, and cost controls. No additional infrastructure to configure, no new security model to learn. Codex on Amazon Bedrock (Limited preview) lets you access the OpenAI coding agent within your existing AWS environments, authenticating with your AWS credentials, processing inference through Bedrock, and applying Codex usage toward your AWS cloud commitments. Codex on Bedrock is available through the Bedrock API, starting with the Codex CLI, the Codex desktop app, and a Visual Studio Code extension. Amazon Bedrock Managed Agents, powered by OpenAI (Limited preview) combines OpenAI frontier models with AWS infrastructure to build production-ready OpenAI-powered agents in the cloud, built with the OpenAI harness for faster execution, sharper reasoning, and reliable steering of long-running tasks.

To learn more, visit Top announcements of the What’s Next with AWS, 2026.

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • Amazon EC2 M8in and M8ib instances are now generally available – Powered by custom 6th-gen Intel Xeon Scalable processors and 6th-gen AWS Nitro cards, these instances deliver up to 43% higher performance over M6in and M6ib. M8in offers 600 Gbps network bandwidth, while M8ib delivers up to 300 Gbps EBS bandwidth. Available in US East (N. Virginia), US West (Oregon), Asia Pacific (Tokyo), and Europe (Spain).
  • Amazon EC2 R8in and R8ib instances are now generally available – Memory-optimized instances built on the same 6th-gen Intel Xeon Scalable processors and Nitro cards, with the same 600 Gbps network and 300 Gbps EBS bandwidth profiles. Well-suited for large commercial databases, data lakes, and in-memory databases such as SAP HANA. Available in US East (N. Virginia, Ohio), US West (Oregon), and Europe (Spain).
  • Amazon EC2 C8ine and M8ine instances are now generally available – Network-optimized instances offering up to 2.5x higher packet performance per vCPU and up to 2x higher network throughput for traffic through internet gateways compared to C6in and M6in. Designed for security and network virtual appliances including virtual firewalls, load balancers, and 5G UPF workloads. Available in US East (N. Virginia), US West (Oregon), and Asia Pacific (Tokyo) for C8ine; US East (N. Virginia) and US West (Oregon) for M8ine.
  • Amazon Bedrock AgentCore adds optimization capabilities (Preview) – AgentCore now offers recommendations, batch evaluations, and A/B tests to complete the observe-evaluate-improve loop for agents in production. Recommendations analyze production traces and evaluation outputs to propose optimized system prompts and tool descriptions, which you can validate with batch evaluations against pre-defined test cases or A/B tests against live traffic. Every recommendation requires your approval before it ships.
  • AWS Lambda adds support for Ruby 4.0 – Ruby 4.0, the latest LTS release, is available as a Lambda managed runtime and container base image. It includes support for Lambda advanced logging controls, including JSON structured logs, configurable logging levels, and target CloudWatch log group configuration. Available in all AWS Regions, including China Regions and AWS GovCloud (US).

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts and resources that you might find interesting:

  • Amazon Q Developer end-of-support announcement – Amazon Q Developer IDE plugins and paid subscriptions will reach end of support on April 30, 2027, giving customers 12 months to transition to Kiro. New signups will be blocked starting May 15, 2026, although existing subscriptions can continue to add users. Starting May 29, 2026, Opus 4.6 will no longer be available on Q Developer Pro; Opus 4.5 and other existing models remain available, and the latest coding models including Opus 4.7 are available exclusively on Kiro. Amazon Q Developer in the AWS Management Console and first-party AWS experiences (documentation, mobile app, Slack, and Microsoft Teams) are not affected.
  • AWS 10,000 AIdeas Competition: Meet the Winners – AWS announced the 20 winners of the 10,000 AIdeas Competition, a global challenge where builders submitted AI applications built entirely with Kiro and the AWS Free Tier, with submissions from 115 countries narrowed down through four rounds of evaluation and two rounds of community voting. Winners span Global Champions, Regional Champions, Innovation Awards, and Creative Track categories, with cash prizes and AWS credits awarded across each tier.
  • AWS Student Builder Groups – AWS Cloud Clubs is evolving to AWS Student Builder Groups. The community now spans 600+ colleges and universities across 63 countries. Existing Cloud Club memberships, badges, and progress carry forward, and Cloud Club Captains become Group Leaders. Membership is open to any learner 18 or older. You can find a group near you on AWS Builder Center or apply to launch a new group on your campus.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

Visit the AWS Builder Center to meet other builders, contribute solutions, and find resources that help you keep building. You can also browse upcoming AWS-led in-person and virtual events, plus developer-focused sessions.

— Esra

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!
Troubleshooting environment with AI analysis in AWS Elastic Beanstalk

Post Syndicated from Chandu Utlapalli original https://aws.amazon.com/blogs/devops/troubleshooting-environment-with-ai-analysis-in-aws-elastic-beanstalk/

Introduction

AWS Elastic Beanstalk simplifies the process of deploying and scaling web applications. You upload your code, and Elastic Beanstalk handles capacity provisioning, load balancing, auto scaling, and application health monitoring.

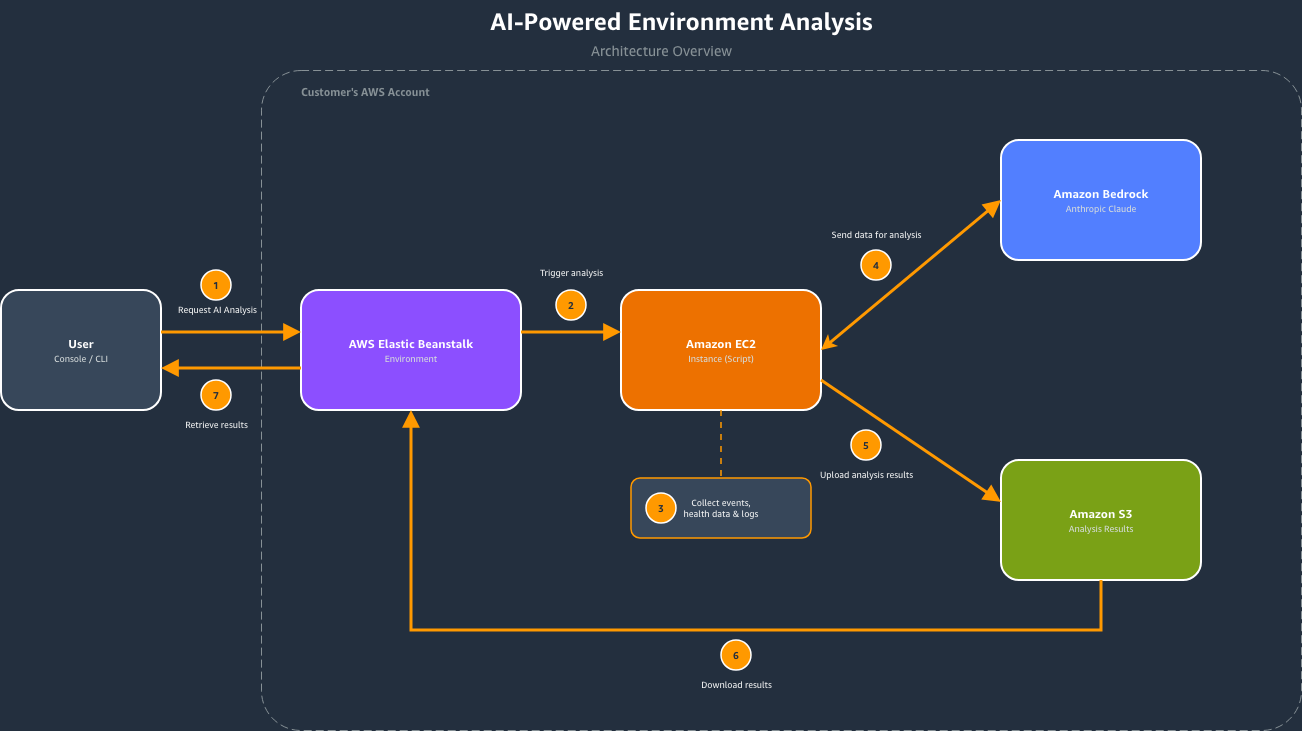
Elastic Beanstalk now offers AI Analysis to help troubleshoot environment health issues. When you request an analysis, Elastic Beanstalk triggers a script on the Amazon EC2 instance in your environment. The script collects environment events, health data, and instance logs, sends them to Amazon Bedrock for analysis, and uploads the results to Amazon S3. The result is a set of step-by-step troubleshooting recommendations tailored to your environment’s specific issues, helping you reduce mean time to resolution (MTTR).

In the Elastic Beanstalk console, the AI Analysis button appears on the environment overview page when your environment’s health status changes to Warning, Degraded, or Severe. AI analysis is also accessible from the logs page in the console, the AWS CLI, or the EB CLI.

Prerequisites

Before getting started, ensure that you have the following:

  • An AWS account with access to AWS Elastic Beanstalk and Amazon Bedrock.
  • A supported Elastic Beanstalk platform version – AI analysis is available on Amazon Linux 2 and AL2023 based platform versions released on or after February 16, 2026. Update your environment to a supported platform version if needed.
  • Instance profile with required permissions – The managed policies AWSElasticBeanstalkWebTier, AWSElasticBeanstalkWorkerTier, and AWSElasticBeanstalkMulticontainerDocker now include the necessary permissions for AI analysis. Attach one or more of these managed policies to your environment’s instance profile based on your environment tier. If you use a custom instance profile, ensure it includes the following permissions:
    • bedrock:InvokeModel
    • bedrock:ListFoundationModels
    • elasticbeanstalk:DescribeEvents
    • elasticbeanstalk:DescribeEnvironmentHealth
  • AWS CLI installed and configured with appropriate permissions. See Installing the AWS CLI.
  • Anthropic use case details – AI analysis uses Anthropic Claude models through Amazon Bedrock. Anthropic requires you to submit a one-time use case details form before you can invoke their models. To submit this form, select an Anthropic model from the model catalog in the Amazon Bedrock console, or call the PutUseCaseForModelAccess API. You only need to do this once per AWS account. If you submit the form from the AWS Organizations management account, it automatically covers member accounts in the organization. For more information, see Access Amazon Bedrock foundation models.
  • GovCloud Regions – If you are using AWS GovCloud (US) Regions, you must enable access to the latest Anthropic Claude Sonnet and/or Opus model in Amazon Bedrock before using AI analysis. For instructions on enabling model access in GovCloud Regions, see Manage access to Amazon Bedrock foundation models. For information about the latest available Anthropic Claude Sonnet and/or Opus model, see Supported Regions and models for inference profiles.

Solution Overview

In the following sections, we demonstrate how to use AI Analysis to diagnose a Node.js application that fails after a deployment.

  1. Create a working environment: Deploy a Node.js application to Elastic Beanstalk using the code snippets provided below.
  2. Break the environment: Update the application with code that requires missing environment variables. This causes the environment health status to transition to Degraded.
  3. Use AI Analysis: Request an AI Analysis from the Elastic Beanstalk console or the AWS CLI to identify the root cause of the health degradation.
  4. Apply the fix and verify: Apply the recommendations generated by AI Analysis and confirm that the environment health returns to Ok.

The following figure shows how AI Analysis works:

Figure 1 – AI Analysis architecture

  1. You initiate a request through the Elastic Beanstalk console (AI Analysis button) or the AWS CLI (RequestEnvironmentInfo API with InfoType set to “analyze”).
  2. Elastic Beanstalk collects environment data, analyzes it using Amazon Bedrock (a fully managed service that provides access to foundation models through API), and stores the results in Amazon S3.
  3. You retrieve the results through the console or the RetrieveEnvironmentInfo API using CLI.

Walkthrough

Follow the steps below to set up the sample application, break it, troubleshoot with AI Analysis, and restore the environment to a healthy state.

To try this feature, open your terminal and follow the steps below to create a sample Elastic Beanstalk environment. First, set the following variables. Replace the values with your own unique S3 bucket name and the latest Node.js solution stack for your region. To find the latest solution stack, run aws elasticbeanstalk list-available-solution-stacks.

S3_BUCKET="your-unique-bucket-name"

SOLUTION_STACK_NAME="64bit Amazon Linux 2023 v6.9.0 running Node.js 22"

Setting up the application

We use two versions of a simple Node.js application. The first version (v1-working) is a basic HTTP server that responds to requests successfully. The second version (v2-broken) introduces a dependency on environment variables that are not configured in the Elastic Beanstalk environment, simulating a common deployment issue.

Create a project directory:

mkdir test-app && cd test-app

Create the working application file (v1-working):

cat << 'EOF' > workingapp.js
const http = require('http');

const server = http.createServer((req, res) => {
    res.writeHead(200, { 'Content-Type': 'application/json' });
    res.end(JSON.stringify({ status: 'healthy', message: 'App is running' }));
});

const port = process.env.PORT || 8080;
server.listen(port, () => {
    console.log(`Server running on port ${port}`);
});
EOF

Create the broken application file (v2-broken):

cat << 'EOF' > brokenapp.js
const http = require('http');

// Application requires these environment variables to function
const VAR_1 = process.env.TEST_VARIABLE_1;
const VAR_2 = process.env.TEST_VARIABLE_2;
const VAR_3 = process.env.TEST_VARIABLE_3;

if (!VAR_1 || !VAR_2 || !VAR_3) {
    throw new Error(
        `Missing required environment variables. ` +
        `TEST_VARIABLE_1: ${VAR_1 ? 'set' : 'MISSING'}, ` +
        `TEST_VARIABLE_2: ${VAR_2 ? 'set' : 'MISSING'}, ` +
        `TEST_VARIABLE_3: ${VAR_3 ? 'set' : 'MISSING'}`
    );
}

const server = http.createServer((req, res) => {
    res.writeHead(200, { 'Content-Type': 'application/json' });
    res.end(JSON.stringify({ status: 'healthy', db: VAR_1 }));
});

const port = process.env.PORT || 8080;
server.listen(port, () => {
    console.log(`Server running on port ${port}`);
});
EOF

Create the package.json:

cat << 'EOF' > package.json
{
  "name": "test-app",
  "version": "1.0.0",
  "description": "Sample app that requires environment variables",
  "main": "app.js",
  "scripts": {
    "start": "node app.js"
  }
}
EOF

Create the working application source bundle:

cp workingapp.js app.js

zip -r nodejs-working-app.zip app.js package.json

Create the broken application source bundle:

cp brokenapp.js app.js

zip -r nodejs-broken-app.zip app.js package.json

Step 1: Create a working environment

First, create the Elastic Beanstalk application and deploy the working version.

Create an S3 bucket:

aws s3 mb s3://$S3_BUCKET --region us-east-1

Upload the working application source bundle:

aws s3 cp nodejs-working-app.zip s3://$S3_BUCKET/nodejs-working-app.zip

Create the Elastic Beanstalk application:

aws elasticbeanstalk create-application \
    --application-name test-app \
    --description "Test application" \
    --region us-east-1

Create the application version:

aws elasticbeanstalk create-application-version \
    --application-name test-app \
    --version-label v1-working \
    --source-bundle S3Bucket="$S3_BUCKET",S3Key="nodejs-working-app.zip" \
    --region us-east-1

Create the environment with the working version:

aws elasticbeanstalk create-environment \
    --application-name test-app \
    --environment-name test-app-env \
    --solution-stack-name "$SOLUTION_STACK_NAME" \
    --version-label v1-working \
    --option-settings \
        Namespace=aws:elasticbeanstalk:environment,OptionName=EnvironmentType,Value=SingleInstance \
        Namespace=aws:autoscaling:launchconfiguration,OptionName=IamInstanceProfile,Value=aws-elasticbeanstalk-ec2-role \
    --region us-east-1

Once your environment is created, verify the health:

aws elasticbeanstalk describe-environment-health \
    --environment-name test-app-env \
    --attribute-names All \
    --region us-east-1

Output:

{
    "EnvironmentName": "test-app-env",
    "HealthStatus": "Ok",
    "Status": "Ready",
    "Color": "Green",
    "Causes": [
        "Initialization completed 31 seconds ago and took 2 minutes."
    ],
    "ApplicationMetrics": {
        "RequestCount": 0
    },
    "InstancesHealth": {
        "NoData": 0,
        "Unknown": 0,
        "Pending": 0,
        "Ok": 1,
        "Info": 0,
        "Warning": 0,
        "Degraded": 0,
        "Severe": 0
    },
    "RefreshedAt": "2026-03-25T16:39:11Z"
}

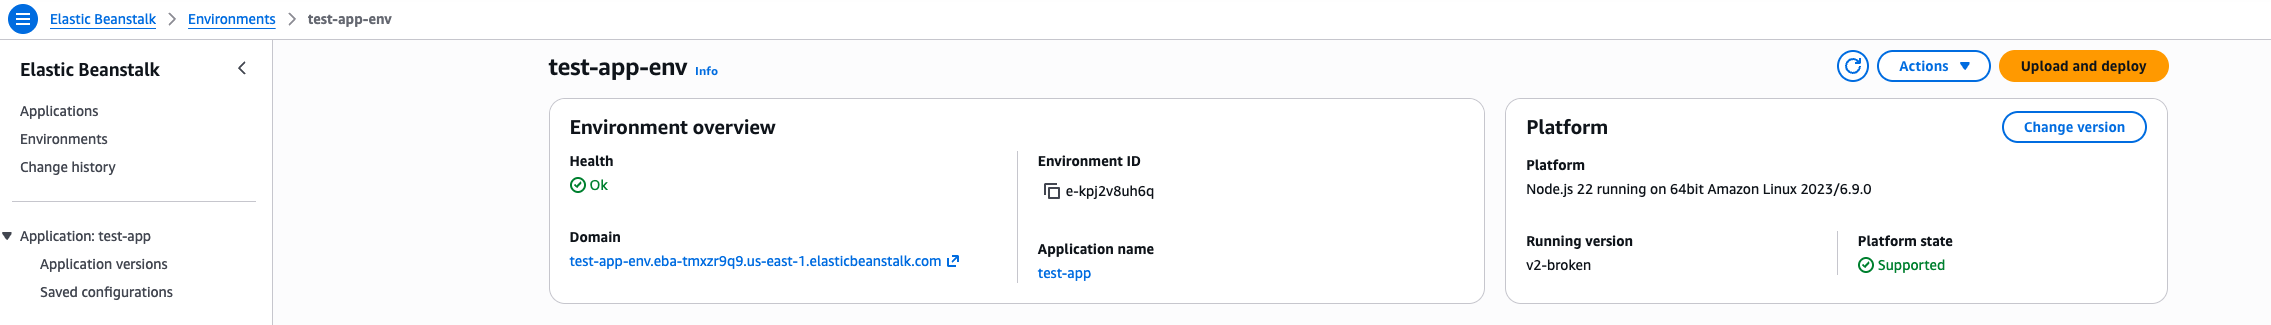
Figure 2 – Environment health showing Ok (Green) status after initial deployment

Step 2: Break the environment

Now, deploy the broken version that requires missing environment variables.

Upload the broken version:

aws s3 cp nodejs-broken-app.zip s3://$S3_BUCKET/nodejs-broken-app.zip

Create the broken application version:

aws elasticbeanstalk create-application-version \
    --application-name test-app \
    --version-label v2-broken \
    --source-bundle S3Bucket="$S3_BUCKET",S3Key="nodejs-broken-app.zip" \
    --region us-east-1

Deploy the broken version:

aws elasticbeanstalk update-environment \
    --environment-name test-app-env \
    --version-label v2-broken \
    --region us-east-1

Within seconds of the deployment completing, the environment health transitions from Ok to Degraded:

aws elasticbeanstalk describe-environment-health \
    --environment-name test-app-env \
    --attribute-names All \
    --region us-east-1

Output:

{
    "EnvironmentName": "test-app-env",
    "HealthStatus": "Degraded",
    "Status": "Ready",
    "Color": "Red",
    "Causes": [
        "Impaired services on all instances."
    ],
    "ApplicationMetrics": {
        "RequestCount": 0
    },
    "InstancesHealth": {
        "NoData": 0,
        "Unknown": 0,
        "Pending": 0,
        "Ok": 0,
        "Info": 0,
        "Warning": 0,
        "Degraded": 0,
        "Severe": 1
    },
    "RefreshedAt": "2026-03-25T16:43:19Z"
}

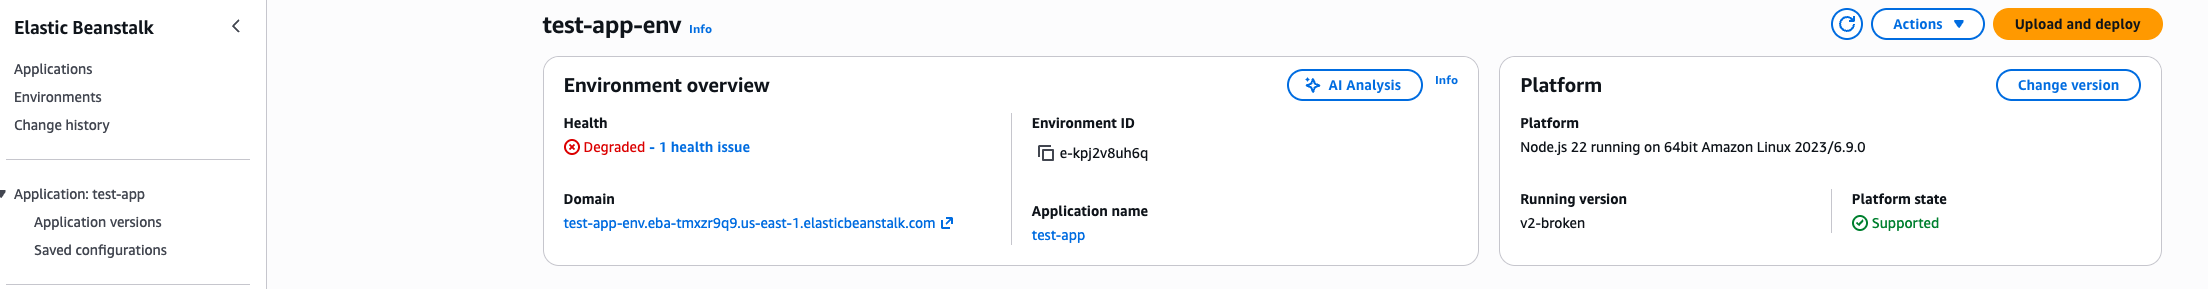
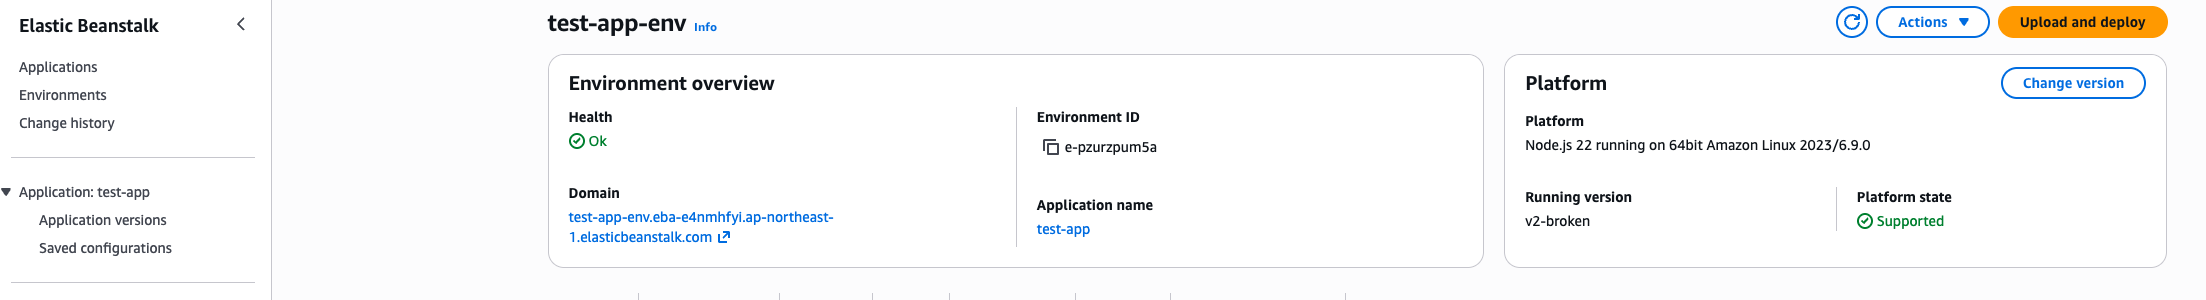
Figure 3 – Environment health showing Degraded (Red) status with the AI Analysis button visible

Step 3: Use AI Analysis

Request AI analysis from the AWS CLI or the Elastic Beanstalk console. Both methods produce the same results. The CLI approach is useful for automation and scripting, while the console provides a visual workflow where you can view results directly on the environment page. We’ll cover both options below.

Using the AWS CLI

Request the analysis:

aws elasticbeanstalk request-environment-info \
    --environment-name test-app-env \
    --info-type analyze \
    --region us-east-1

Once the request environment operation is completed, retrieve the results:

aws elasticbeanstalk retrieve-environment-info \
    --environment-name test-app-env \
    --info-type analyze \
    --region us-east-1

The response includes an EnvironmentInfo array with a Message field containing a pre-signed S3 URL to the analysis results:

{
    "EnvironmentInfo": [
        {
            "InfoType": "analyze",
            "Ec2InstanceId": "i-1234567890abcdef0",
            "SampleTimestamp": "2026-03-20T20:49:22.763Z",
            "Message": "https://elasticbeanstalk-us-east-1-123456789012.s3.us-east-1.amazonaws.com/resources/environments/logs/analyze/..."
        }
    ]
}

Download and view the analysis:

ANALYSIS_URL=$(aws elasticbeanstalk retrieve-environment-info \
    --environment-name test-app-env \
    --info-type analyze \
    --region us-east-1 \
    --query 'sort_by(EnvironmentInfo, &SampleTimestamp)[-1].Message' \
    --output text)

curl -s "$ANALYSIS_URL"

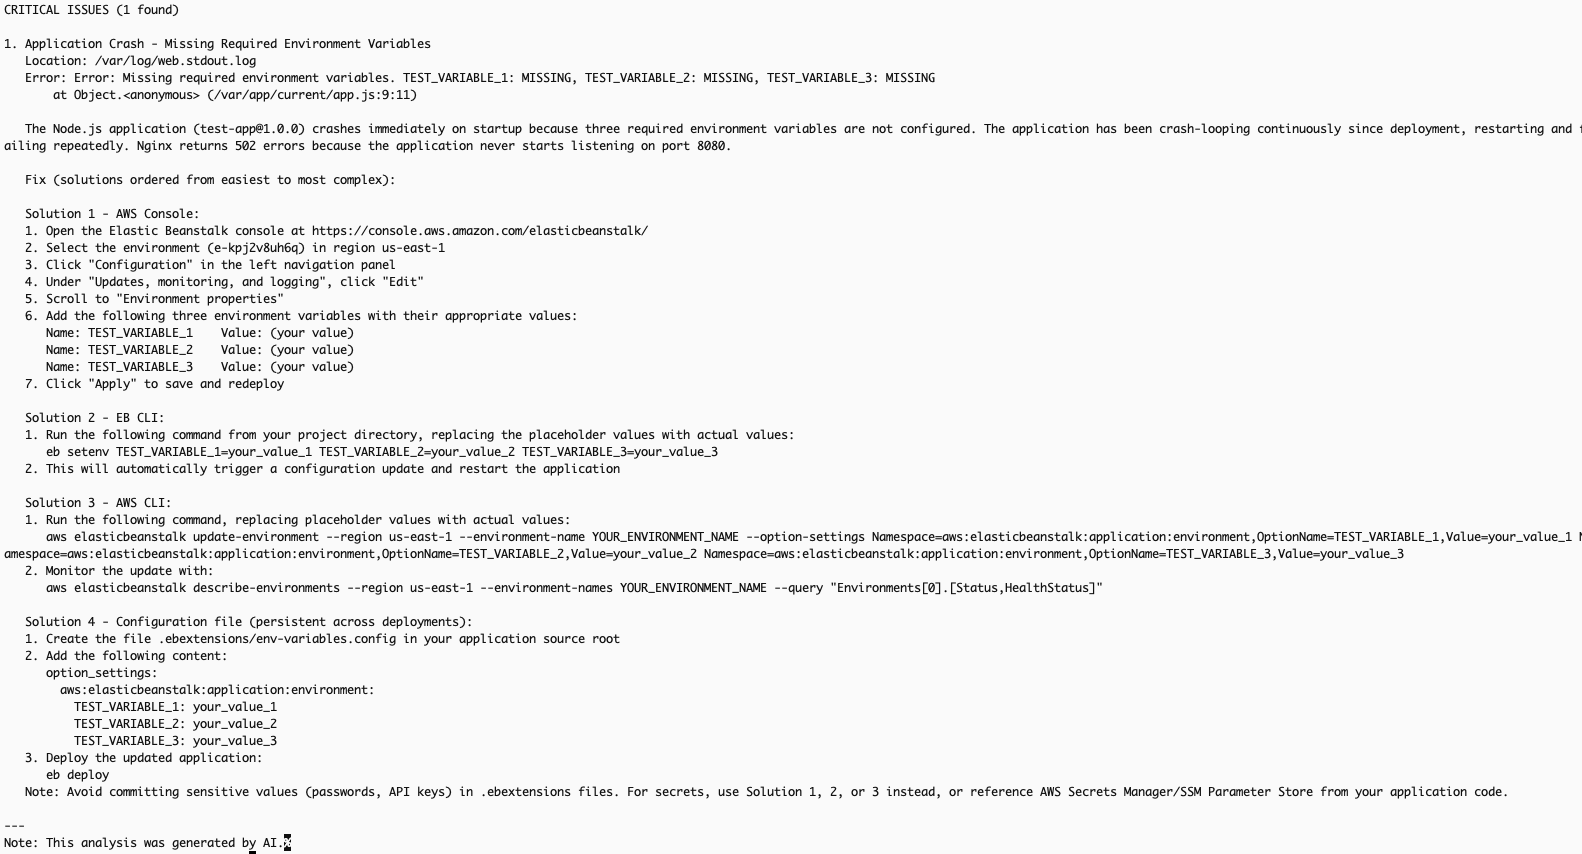
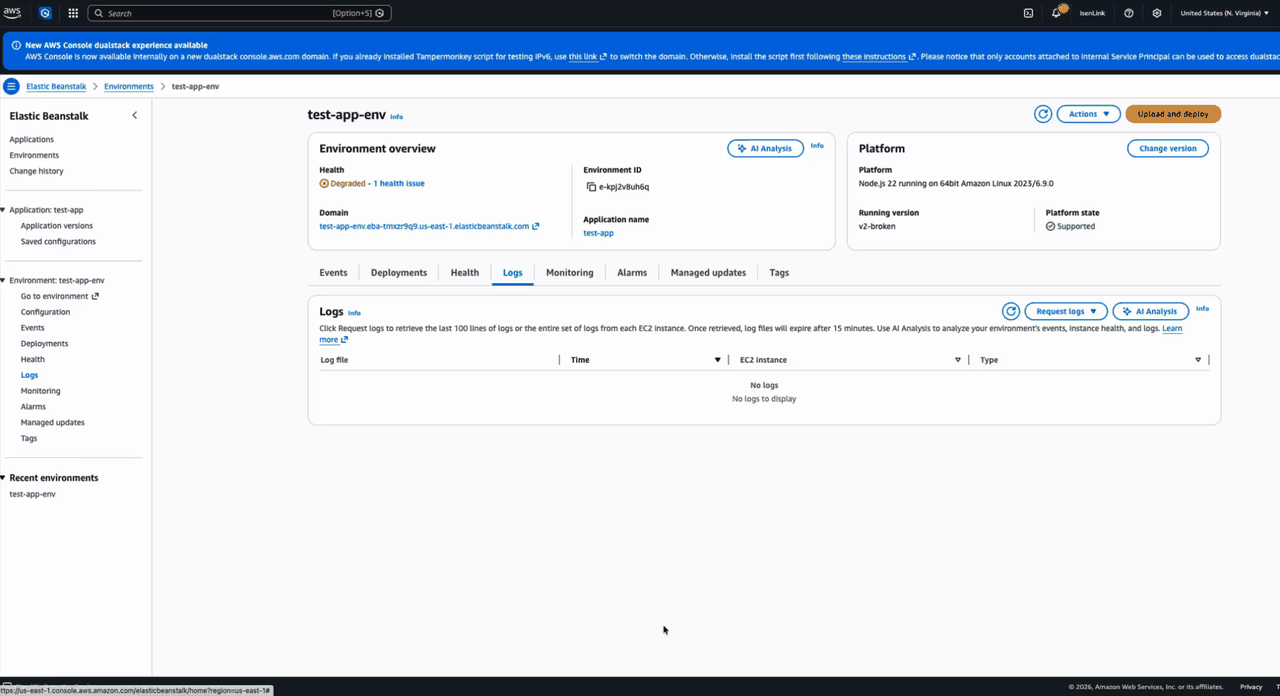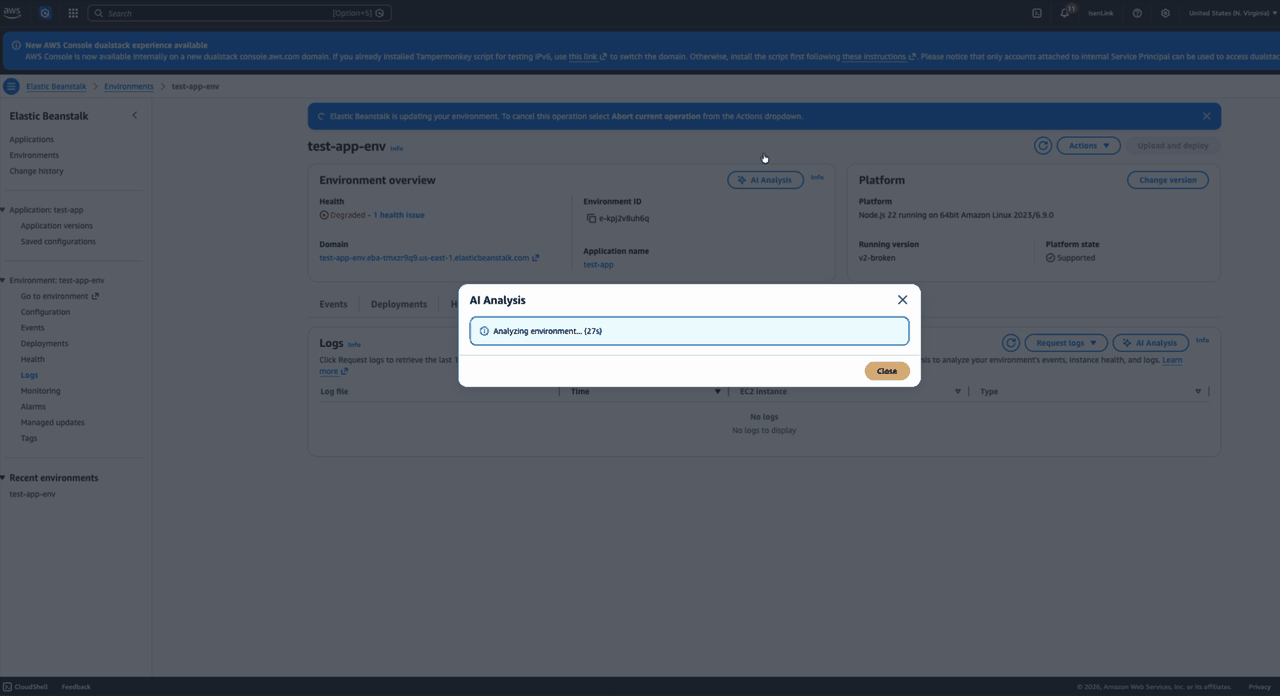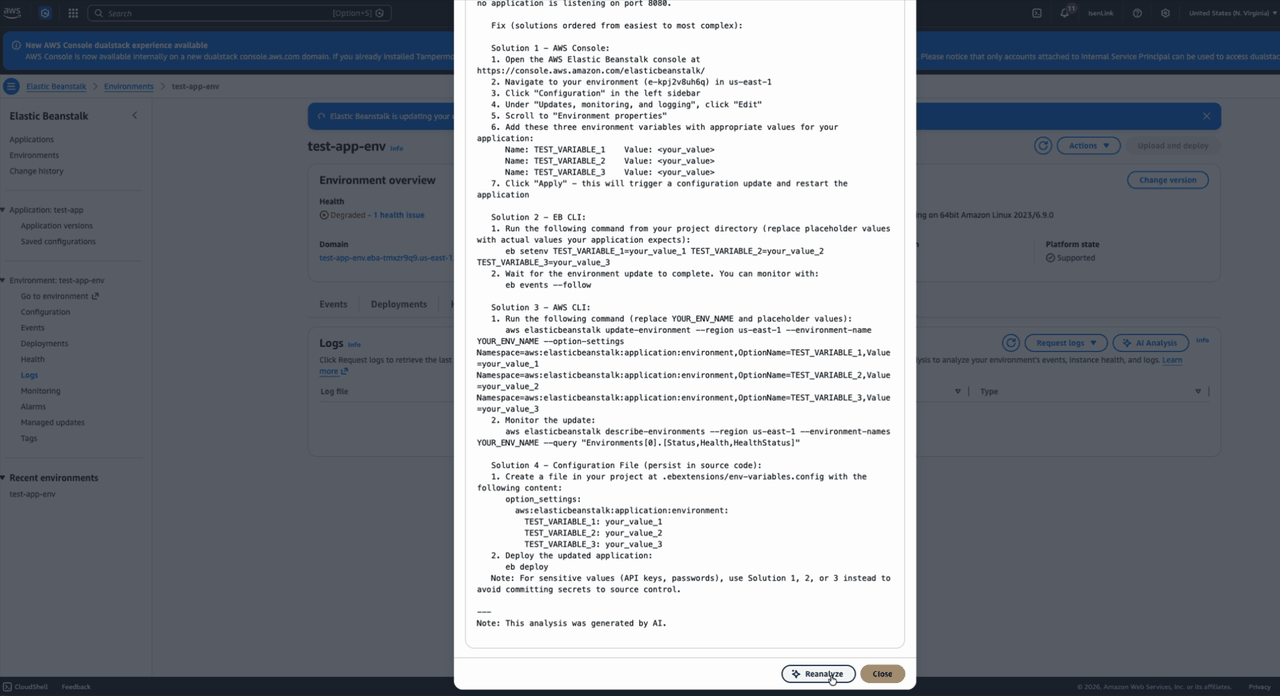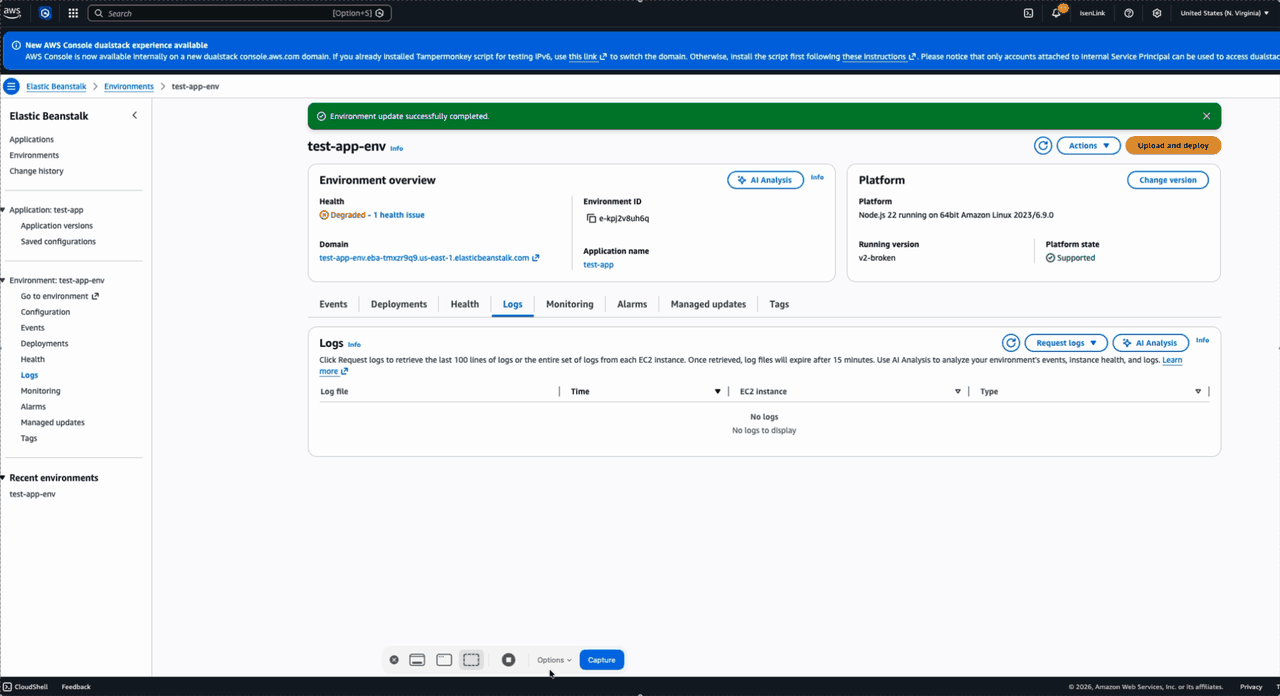
Figure 4 – AI analysis output retrieved via AWS CLI

Using the Elastic Beanstalk console

When your environment’s health status is Warning, Degraded, or Severe, the AI Analysis button appears in the environment overview section of the Elastic Beanstalk console.

  1. Navigate to the Elastic Beanstalk console.
  2. Select your environment (test-app-env).
  3. On the environment overview page, locate the AI Analysis button that appears when the health status indicates an issue.
  4. Choose AI Analysis to initiate the analysis.

Video 1 – Requesting AI analysis from the Elastic Beanstalk console

If you want to restart the analysis workflow, you can click on the Reanalyze button to start a new analysis.

Step 4: Apply the fix and verify

The AI analysis identified that the application crashes because the environment does not have three required environment variables configured: TEST_VARIABLE_1, TEST_VARIABLE_2, and TEST_VARIABLE_3. As recommended by the AI analysis, set these environment variables to resolve the issue:

aws elasticbeanstalk update-environment \
    --environment-name test-app-env \
    --option-settings \
        Namespace=aws:elasticbeanstalk:application:environment,OptionName=TEST_VARIABLE_1,Value=value1 \
        Namespace=aws:elasticbeanstalk:application:environment,OptionName=TEST_VARIABLE_2,Value=value2 \
        Namespace=aws:elasticbeanstalk:application:environment,OptionName=TEST_VARIABLE_3,Value=value3 \
    --region us-east-1

After the environment update completes, the application starts successfully and the environment health returns to Ok:

aws elasticbeanstalk describe-environment-health \
    --environment-name test-app-env \
    --attribute-names All \
    --region us-east-1

Output:

{
    "EnvironmentName": "test-app-env",
    "HealthStatus": "Ok",
    "Status": "Ready",
    "Color": "Green",
    "Causes": [
        "Configuration update completed 72 seconds ago and took 54 seconds."
    ],
    "ApplicationMetrics": {
        "RequestCount": 0
    },
    "InstancesHealth": {
        "NoData": 0,
        "Unknown": 0,
        "Pending": 0,
        "Ok": 1,
        "Info": 0,
        "Warning": 0,
        "Degraded": 0,
        "Severe": 0
    },
    "RefreshedAt": "2026-03-25T17:42:47Z"
}

Figure 5 – Environment health restored to Ok (Green) after setting environment variables

Note: The steps in this walkthrough can also be performed using the EB CLI. For more information, see the EB CLI Command Reference.

Best practices

Consider these recommendations to get the most out of AI analysis for your environments.

  1. Use supported platform versions: Ensure your environment is running an Amazon Linux 2 or AL2023 platform version released on or after February 16, 2026. Update your platform if you don’t see the AI Analysis option.
  2. Implement fixes incrementally: If the analysis recommends multiple actions, implement them one at a time to isolate which change resolves the issue.
  3. Review data privacy considerations: The analysis sends environment events and logs to Amazon Bedrock running in your account. For more information about how Amazon Bedrock handles your data, see the Amazon Bedrock security documentation.

Cleaning up

Terminate the environment:

aws elasticbeanstalk terminate-environment \
    --environment-name test-app-env \
    --region us-east-1

Delete the application (after the environment is terminated):

aws elasticbeanstalk delete-application \
    --application-name test-app \
    --terminate-env-by-force \
    --region us-east-1

Delete the S3 bucket used for source bundles:

aws s3 rb s3://$S3_BUCKET --force --region us-east-1

Remove the local project directory:

rm -rf test-app

Conclusion

AI-powered environment analysis in AWS Elastic Beanstalk significantly reduces the time and effort required to diagnose environment health issues. Instead of manually parsing through log files and cross-referencing documentation, you can now get targeted, actionable recommendations with a click of the AI Analysis button in the console or an API call.

Whether you prefer using the Elastic Beanstalk console for visual workflows or the AWS CLI/EB CLI for scripting and automation, AI analysis provides a consistent experience that helps you quickly identify root causes and resolve issues.

To learn more about AI-powered environment analysis, see the AWS Elastic Beanstalk Developer Guide. To learn more about AWS Elastic Beanstalk, visit the product page.

About the Author

Chandu Utlapalli

Chandu is a Software Development Engineer at AWS, working on the Elastic Beanstalk service. He focuses on building scalable cloud solutions and integrating AI capabilities to enhance developer productivity and cloud operations. Outside of work, Chandu enjoys playing cricket.

AWS Weekly Roundup: Claude Sonnet 4.6 in Amazon Bedrock, Kiro in GovCloud Regions, new Agent Plugins, and more (February 23, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-sonnet-4-6-in-amazon-bedrock-kiro-in-govcloud-regions-new-agent-plugins-and-more-february-23-2026/

Last week, my team met many developers at Developer Week in San Jose. My colleague, Vinicius Senger delivered a great keynote about renascent software—a new way of building and evolving applications where humans and AI collaborate as co-developers using Kiro. Other colleagues spoke about building and deploying production-ready AI agents. Everyone stayed to ask and hear the questions related to agent memory, multi-agent patterns, meta-tooling and hooks. It was interesting how many developers were actually building agents.

We are continuing to meet developers and hear their feedback at third-party developer conferences. You can meet us at the dev/nexus, the largest and longest-running Java ecosystem conference on March 4-6 in Atlanta. My colleague, James Ward will speak about building AI Agents with Spring and MCP, and Vinicius Senger and Jonathan Vogel will speak about 10 tools and tips to upgrade your Java code with AI. I’ll keep sharing places for you to connect with us.

Last week’s launches
Here are some of the other announcements from last week:

  • Claude Sonnet 4.6 model in Amazon Bedrock – You can now use Claude Sonnet 4.6 which offers frontier performance across coding, agents, and professional work at scale. Claude Sonnet 4.6 approaches Opus 4.6 intelligence at a lower cost. It enables faster, high-quality task completion, making it ideal for high-volume coding and knowledge work use cases.
  • Amazon EC2 Hpc8a instances powered by 5th Gen AMD EPYC processors – You can use new Hpc8a instances delivering up to 40% higher performance, increased memory bandwidth, and 300 Gbps Elastic Fabric Adapter networking. You can accelerate compute-intensive simulations, engineering workloads, and tightly coupled HPC applications.
  • Amazon SageMaker Inference for custom Amazon Nova models – You can now configure the instance types, auto-scaling policies, and concurrency settings for custom Nova model deployments with Amazon SageMaker Inference to best meet your needs.
  • Nested virtualization on virtual Amazon EC2 instances – You can create nested virtual machines by running KVM or Hyper-V on virtual EC2 instances. You can leverage this capability for use cases such as running emulators for mobile applications, simulating in-vehicle hardware for automobiles, and running Windows Subsystem for Linux on Windows workstations.
  • Server-Side Encryption by default in Amazon Aurora – Amazon Aurora further strengthens your security posture by automatically applying server-side encryption by default to all new databases clusters using AWS-owned keys. This encryption is fully managed, transparent to users, and with no cost or performance impact.
  • Kiro in AWS GovCloud (US) Regions – You can use Kiro for the development teams behind government missions. Developers in regulated environments can now leverage Kiro’s agentic AI tool with the rigorous security controls required.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Additional updates
Here are some additional news items that you might find interesting:

  • Introducing Agent Plugins for AWS – You can see how new open-source Agent Plugins for AWS extend coding agents with skills for deploying applications to AWS. Using the deploy-on-aws plugin, you can generate architecture recommendations, cost estimates, and infrastructure-as-code directly from your coding agent.
  • A chat with Byron Cook on automated reasoning and trust in AI systems – You can hear how to verify AI systems doing the right thing using automated reasoning when they generate code or manage critical decisions. Byron Cook’s team has spent a decade proving correctness in AWS and apply those techniques to agentic systems.
  • Best practices for deploying AWS DevOps Agent in production – You can read best practices for setting up DevOps Agent Spaces that balance investigation capability with operational efficiency. According to Swami Sivasubramanian, AWS DevOps Agent, a frontier agent that resolves and proactively prevents incidents, has handled thousands of escalations, with an estimated root cause identification rate of over 86% within Amazon.

From AWS community
Here are my personal favorite posts from AWS community:

Join the AWS Builder Center to connect with community, share knowledge, and access content that supports your development.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS Summits – Join AWS Summits in 2026, free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).
  • Amazon Nova AI Hackathon – Join developers worldwide to build innovative generative AI solutions using frontier foundation models and compete for $40,000 in prizes across five categories including agentic AI, multimodal understanding, UI automation, and voice experiences during this six-week challenge from February 2nd to March 16th, 2026.
  • AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders, featuring technical discussions, workshops, and hands-on labs. Upcoming events include Ahmedabad (February 28), JAWS Days in Tokyo (March 7), Chennai (March 7), Slovakia (March 11), and Pune (March 21).

Browse here for upcoming AWS led in-person and virtual events, startup events, and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!
— Channy

Amazon EC2 Hpc8a Instances powered by 5th Gen AMD EPYC processors are now available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-ec2-hpc8a-instances-powered-by-5th-gen-amd-epyc-processors-are-now-available/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) Hpc8a instances, a new high performance computing (HPC) optimized instance type powered by latest 5th Generation AMD EPYC processors with a maximum frequency of up to 4.5 GHz. These instances are ideal for compute-intensive tightly coupled HPC workloads, including computational fluid dynamics, simulations for faster design iterations, high-resolution weather modeling within tight operational windows, and complex crash simulations that require rapid time-to-results.

The new Hpc8a instances deliver up to 40% higher performance, 42% greater memory bandwidth, and up to 25% better price-performance compared to previous generation Hpc7a instances. Customers benefit from the high core density, memory bandwidth, and low-latency networking that helped them scale efficiently and reduce job completion times for their compute-intensive simulation workloads.

Hpc8a instances
Hpc8a instances are available with 192 cores, 768 GiB memory, and 300 Gbps Elastic Fabric Adapter (EFA) networking to run applications requiring high levels of inter node communications at scale.

Instance Name Physical Cores Memory (Gib) EFA Network Bandwidth (Gbps) Network Bandwidth (Gbps) Attached Storage
Hpc8a.96xlarge 192 768 Up to 300 75 EBS Only

Hpc8a instances are available in a single 96xlarge size with a 1:4 core-to-memory ratio. You will have the capability to right size based on HPC workload requirements by customizing the number of cores needed at launch instances. These instances also use sixth-generation AWS Nitro cards, which offload CPU virtualization, storage, and networking functions to dedicated hardware and software, enhancing performance and security for your workloads.

You can use Hpc8a instances with AWS ParallelCluster and AWS Parallel Computing Service (AWS PCS) to simplify workload submission and cluster creation and Amazon FSx for Lustre for sub-millisecond latencies and up to hundreds of gigabytes per second of throughput for storage. To achieve the best performance for HPC workloads, these instances have Simultaneous Multithreading (SMT) disabled.

Now available
Amazon EC2 Hpc8a instances are now available in US East (Ohio) and Europe (Stockholm) AWS Regions. For Regional availability and a future roadmap, search the instance type in the CloudFormation resources tab of AWS Capabilities by Region.

You can purchase these instances as On-Demand Instances and Savings Plan. To learn more, visit the Amazon EC2 Pricing page.

Give Hpc8a instances a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 Hpc8a instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: Claude Opus 4.6 in Amazon Bedrock, AWS Builder ID Sign in with Apple, and more (February 9, 2026)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-opus-4-6-in-amazon-bedrock-aws-builder-id-sign-in-with-apple-and-more-february-9-2026/

Here are the notable launches and updates from last week that can help you build, scale, and innovate on AWS.

Last week’s launches
Here are the launches that got my attention this week.

Let’s start with news related to compute and networking infrastructure:

  • Introducing Amazon EC2 C8id, M8id, and R8id instances: These new Amazon EC2 C8id, M8id, and R8id instances are powered by custom Intel Xeon 6 processors. These instances offer up to 43% higher performance and 3.3x more memory bandwidth compared to previous generation instances.
  • AWS Network Firewall announces new price reductions: The service has added the hourly and data processing discounts on NAT Gateways that are service-chained with Network Firewall secondary endpoints. Additionally, AWS Network Firewall has removed additional data processing charges for Advanced Inspection, which enables Transport Layer Security (TLS) inspection of encrypted network traffic.
  • Amazon ECS adds Network Load Balancer support for Linear and Canary deployments: Applications that commonly use NLB, such as those requiring TCP/UDP-based connections, low latency, long-lived connections, or static IP addresses, can take advantage of managed, incremental traffic shifting natively from ECS when rolling out updates.
  • AWS Config now supports 30 new resource types: These range across key services including Amazon EKS, Amazon Q, and AWS IoT. This expansion provides greater coverage over your AWS environment, enabling you to more effectively discover, assess, audit, and remediate an even broader range of resources.
  • Amazon DynamoDB global tables now support replication across multiple AWS accounts: DynamoDB global tables are a fully managed, serverless, multi-Region, and multi-active database. With this new capability, you can replicate tables across AWS accounts and Regions to improve resiliency, isolate workloads at the account level, and apply distinct security and governance controls.
  • Amazon RDS now provides an enhanced console experience to connect to a database: The new console experience provides ready-made code snippets for Java, Python, Node.js, and other programming languages as well as tools like the psql command line utility. These code snippets are automatically adjusted based on your database’s authentication settings. For example, if your cluster uses IAM authentication, the generated code snippets will use token-based authentication to connect to the database. The console experience also includes integrated CloudShell access, offering the ability to connect to your databases directly from within the RDS console.

Then, I noticed three news items related to security and how you authenticate on AWS:

  • AWS Builder ID now supports Sign in with Apple: AWS Builder ID, your profile for accessing AWS applications including AWS Builder Center, AWS Training and Certification, AWS re:Post, AWS Startups, and Kiro, now supports sign-in with Apple as a social login provider. This expansion of sign-in options builds on the existing sign-in with Google capability, providing Apple users with a streamlined way to access AWS resources without managing separate credentials on AWS.
  • AWS STS now supports validation of select identity provider specific claims from Google, GitHub, CircleCI and OCI: You can reference these custom claims as condition keys in IAM role trust policies and resource control policies, expanding your ability to implement fine-grained access control for federated identities and help you establish your data perimeters. This enhancement builds upon IAM’s existing OIDC federation capabilities, which allow you to grant temporary AWS credentials to users authenticated through external OIDC-compatible identity providers.
  • AWS Management Console now displays Account Name on the Navigation bar for easier account identification: You now have an easy way to identify your accounts at a glance. You can now quickly distinguish between accounts visually using the account name that appears in the navigation bar for all authorized users in that account.
  • Amazon CloudFront announces mutual TLS support for origins: Now with origin mTLS support, you can implement a standardized, certificate-based authentication approach that eliminates operational burden. This enables organizations to enforce strict authentication for their proprietary content, ensuring that only verified CloudFront distributions can establish connections to backend infrastructure ranging from AWS origins and on-premises servers to third-party cloud providers and external CDNs.

Finally, there is not a single week without news around AI :

  • Claude Opus 4.6 now available in Amazon Bedrock: Opus 4.6 is Anthropic’s most intelligent model to date and a premier model for coding, enterprise agents, and professional work. Claude Opus 4.6 brings advanced capabilities to Amazon Bedrock customers, including industry-leading performance for agentic tasks, complex coding projects, and enterprise-grade workflows that require deep reasoning and reliability.
  • Structured outputs now available in Amazon Bedrock: Amazon Bedrock now supports structured outputs, a capability that provides consistent, machine-readable responses from foundation models that adhere to your defined JSON schemas. Instead of prompting for valid JSON and adding extra checks in your application, you can specify the format you want and receive responses that match it—making production workflows more predictable and resilient.

Upcoming AWS events
Check your calendars so that you can sign up for this upcoming event:

AWS Community Day Romania (April 23–24, 2026): This community-led AWS event brings together developers, architects, entrepreneurs, and students for more than 10 professional sessions delivered by AWS Heroes, Solutions Architects, and industry experts. Attendees can expect expert-led technical talks, insights from speakers with global conference experience, and opportunities to connect during dedicated networking breaks, all hosted at a premium venue designed to support collaboration and community engagement.

If you’re looking for more ways to stay connected beyond this event, join the AWS Builder Center to learn, build, and connect with builders in the AWS community.

Check back next Monday for another Weekly Roundup.

— seb

Amazon EC2 C8id, M8id, and R8id instances with up to 22.8 TB local NVMe storage are generally available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-ec2-c8id-m8id-and-r8id-instances-with-up-to-22-8-tb-local-nvme-storage-are-generally-available/

Last year, we launched the Amazon Elastic Compute Cloud (Amazon EC2) C8i instances, M8i instances, and R8i instances powered by custom Intel Xeon 6 processors available only on AWS with sustained all-core 3.9 GHz turbo frequency. They deliver the highest performance and fastest memory bandwidth among comparable Intel processors in the cloud.

Today we’re announcing new Amazon EC2 C8id, M8id, and R8id instances backed by up to 22.8TB of NVMe-based SSD block-level instance storage physically connected to the host server. These instances offer 3 times more vCPUs, memory and local storage compared to previous sixth-generation instances.

These instances deliver up to 43% higher compute performance and 3.3 times more memory bandwidth compared to previous sixth-generation instances. They also deliver up to 46% higher performance for I/O intensive database workloads, and up to 30% faster query results for I/O intensive real-time data analytics compared to previous sixth generation instances.

  • C8id instances are ideal for compute-intensive workloads, including those that need access to high-speed, low-latency local storage like video encoding, image manipulation, and other forms of media processing.
  • M8id instances are best for workloads that require a balance of compute and memory resources along with high-speed, low-latency local block storage, including data logging, media processing, and medium-sized data stores.
  • R8id instances are designed for memory-intensive workloads such as large-scale SQL and NoSQL databases, in-memory databases, large-scale data analytics, and AI inference.

C8id, M8id, and R8id instances now scale up to 96xlarge (versus 32xlarge sizes in the sixth generation) with up to 384 vCPUs, 3TiB of memory, and 22.8TB of local storage that make it easier to scale up applications and drive greater efficiencies. These instances also offer two bare metal sizes (metal-48xl and metal-96xl), allowing you to right size your instances and deploy your most performance sensitive workloads that benefit from direct access to physical resources.

The instances are available in 11 sizes per family, as well as two bare metal configurations each:

Instance Name vCPUs Memory (GiB) (C/M/R) Local NVMe storage (GB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
large 2 4/8/16* 1 x 118 Up to 12.5 Up to 10
xlarge 4 8/16/32* 1 x 237 Up to 12.5 Up to 10
2xlarge 8 16/32/64* 1 x 474 Up to 15 Up to 10
4xlarge 16 32/64/128* 1 x 950 Up to 15 Up to 10
8xlarge 32 64/128/256* 1 x 1,900 15 10
12xlarge 48 96/192/384* 1 x 2,850 22.5 15
16xlarge 64 128/256/512* 1 x 3,800 30 20
24xlarge 96 192/384/768* 2 x 2,850 40 30
32xlarge 128 256/512/1024* 2 x 3,800 50 40
48xlarge 192 384/768/1536* 3 x 3,800 75 60
96xlarge 384 768/1536/3072* 6 x 3,800 100 80
metal-48xl 192 384/768/1536* 3 x 3,800 75 60
metal-96xl 384 768/1536/3072* 6 x 3,800 100 80

*Memory values are for C8id/M8id/R8id respectively.

These instances support the Instance Bandwidth Configuration (IBC) feature like other eighth-generation instance types, offering flexibility to allocate resources between network and Amazon Elastic Block Store (Amazon EBS) bandwidth. You can scale network or EBS bandwidth by 25%, allocating resources optimally for each workload. These instances also use sixth-generation AWS Nitro cards offloading CPU virtualization, storage, and networking functions to dedicated hardware and software, enhancing performance and security for your workloads.

You can use any Amazon Machine Images (AMIs) that include drivers for the Elastic Network Adapter (ENA) and NVMe to fully utilize the performance and capabilities. All current generation AWS Windows and Linux AMIs come with the AWS NVMe driver installed by default. If you use an AMI that does not have the AWS NVMe driver, you can manually install AWS NVMe drivers.

As I noted in my previous blog post, here are a couple of things to remind you about the local NVMe storage on these instances:

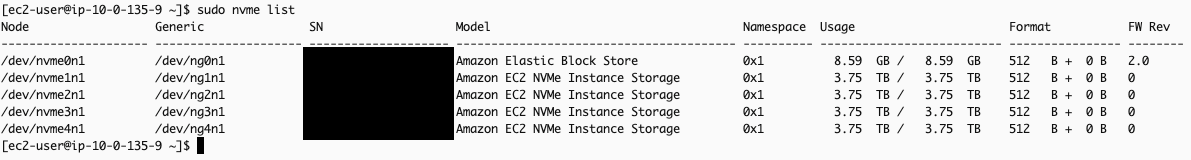
  • You don’t have to specify a block device mapping in your AMI or during the instance launch; the local storage will show up as one or more devices (/dev/nvme[0-26]n1 on Linux) after the guest operating system has booted.
  • Each local NVMe device is hardware encrypted using the XTS-AES-256 block cipher and a unique key. Each key is destroyed when the instance is stopped or terminated.
  • Local NVMe devices have the same lifetime as the instance they are attached to and do not persist after the instance has been stopped or terminated.

To learn more, visit Amazon EBS volumes and NVMe in the Amazon EBS User Guide.

Now available
Amazon EC2 C8id, M8id and R8id instances are available in US East (N. Virginia), US East (Ohio), and US West (Oregon) AWS Regions. R8id instances are additionally available in Europe (Frankfurt) Region. For Regional availability and a future roadmap, search the instance type in the CloudFormation resources tab of AWS Capabilities by Region.

You can purchase these instances as On-Demand Instances, Savings Plans, and Spot Instances. These instances are also available as Dedicated Instances and Dedicated Hosts. To learn more, visit the Amazon EC2 Pricing page.

Give C8id, M8id, and R8id instances a try in the Amazon EC2 console. To learn more, visit the EC2 C8i instances, M8i instances, and R8i instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

Announcing Amazon EC2 G7e instances accelerated by NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/announcing-amazon-ec2-g7e-instances-accelerated-by-nvidia-rtx-pro-6000-blackwell-server-edition-gpus/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) G7e instances that deliver cost-effective performance for generative AI inference workloads and the highest performance for graphics workloads.

G7e instances are accelerated by the NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs and are well suited for a broad range of GPU-enabled workloads including spatial computing and scientific computing workloads. G7e instances deliver up to 2.3 times inference performance compared to G6e instances.

Improvements made compared to predecessors:

  • NVIDIA RTX PRO 6000 Blackwell GPUs — NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs offer two times the GPU memory and 1.85 times the GPU memory bandwidth compared to G6e instances. By using the higher GPU memory offered by G7e instances, you can run medium-sized models of up to 70B parameters with FP8 precision on a single GPU.
  • NVIDIA GPUDirect P2P — For models that are too large to fit into the memory of a single GPU, you can split the model or computations across multiple GPUs. G7e instances reduce the latency of your multi-GPU workloads with support for NVIDIA GPUDirect P2P, which enables direct communication between GPUs over PCIe interconnect. These instances offer the lowest peer to peer latency for GPUs on the same PCIe switch. Additionally, G7e instances offer up to four times the inter-GPU bandwidth compared to L40s GPUs featured in G6e instances, boosting the performance of multi-GPU workloads. These improvements mean you can run inference for larger models across multiple GPUs offering up to 768 GB of GPU memory in a single node.
  • Networking — G7e instances offer four times the networking bandwidth compared to G6e instances, which means you can use the instance for small-scale multi-node workloads. Additionally, multi-GPU G7e instances support NVIDIA GPUDirect Remote Direct Memory Access (RDMA) with Elastic Fabric Adapter (EFA), which reduces the latency of remote GPU-to-GPU communication for multi-node workloads. These instance sizes also support NVIDIA GPUDirectStorage with Amazon FSx for Lustre, which increases throughput by up to 1.2 Tbps to the instances compared to G6e instances, which means you can quickly load your models.

EC2 G7e specifications
G7e instances feature up to 8 NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs with up to 768 GB of total GPU memory (96 GB of memory per GPU) and Intel Emerald Rapids processors. They also support up to 192 vCPUs, up to 1,600 Gbps of network bandwidth, up to 2,048 GiB of system memory, and up to 15.2 TB of local NVMe SSD storage.

Here are the specs:

Instance name
 GPUs GPU memory (GB) vCPUs Memory (GiB) Storage (TB) EBS bandwidth (Gbps) Network bandwidth (Gbps)
g7e.2xlarge 1 96 8 64 1.9 x 1 Up to 5 50
g7e.4xlarge 1 96 16 128 1.9 x 1 8 50
g7e.8xlarge 1 96 32 256 1.9 x 1 16 100
g7e.12xlarge 2 192 48 512 3.8 x 1 25 400
g7e.24xlarge 4 384 96 1024 3.8 x 2 50 800
g7e.48xlarge 8 768 192 2048 3.8 x 4 100 1600

To get started with G7e instances, you can use the AWS Deep Learning AMIs (DLAMI) for your machine learning (ML) workloads. To run instances, you can use AWS Management Console, AWS Command Line Interface (AWS CLI) or AWS SDKs. For a managed experience, you can use G7e instances with Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS). Support for Amazon SageMaker AI is also coming soon.

Now available
Amazon EC2 G7e instances are available today in the US East (N. Virginia) and US East (Ohio) AWS Regions. For Regional availability and a future roadmap, search the instance type in the CloudFormation resources tab of AWS Capabilities by Region.

The instances can be purchased as On-Demand Instances, Savings Plan, and Spot Instances. G7e instances are also available in Dedicated Instances and Dedicated Hosts. To learn more, visit the Amazon EC2 Pricing page.

Give G7e instances a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 G7e instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: Kiro CLI latest features, AWS European Sovereign Cloud, EC2 X8i instances, and more (January 19, 2026)

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-kiro-cli-latest-features-aws-european-sovereign-cloud-ec2-x8i-instances-and-more-january-19-2026/

At the end of 2025 I was happy to take a long break to enjoy the incredible summers that the southern hemisphere provides. I’m back and writing my first post in 2026 which also happens to be my last post for the AWS News Blog (more on this later).

The AWS community is starting the year strong with various AWS re:invent re:Caps being hosted around the globe, with some communities already hosting their AWS Community Day events, the AWS Community Day Tel Aviv 2026 was hosted last week.

Last week’s launches
Here are last week’s launches that caught my attention:

  • Kiro CLI latest features – Kiro CLI now has granular controls for web fetch URLs, keyboard shortcuts for your custom agents, enhanced diff views, and much more. With these enhancements, you can now use allowlists or blocklists to restrict which URLs the agent can access, ensure a frictionless experience when working with multiple specialized agents in a single session, to name a few.
  • AWS European Sovereign Cloud – Following an announcement in 2023 of plans to build a new, independent cloud infrastructure, last week we announced the general availability of the AWS European Sovereign Cloud to all customers. The cloud is ready to meet the most stringent sovereignty requirements of European customers with a comprehensive set of AWS services.
  • Amazon EC2 X8i instances – Previously launched in preview at AWS re:Invent 2025, last week we announced the general availability of new memory-optimized Amazon Elastic Compute Cloud (Amazon EC2) X8i instances. These instances are powered by custom Intel Xeon 6 processors with a sustained all-core turbo frequency of 3.9 GHz, available only on AWS. These SAP certified instances deliver the highest performance and fastest memory bandwidth among comparable Intel processors in the cloud.

Additional updates
These projects, blog posts, and news articles also caught my attention:

  • 5 core features in Amazon Quick Suite – AWS VP Agentic AI Swami Sivasubramanian talks about how he uses Amazon Quick Suite for just about everything. In October 2025 we announced Amazon Quick Suite, a new agentic teammate that quickly answers your questions at work and turns insights into actions for you. Amazon Quick Suite has become one of my favorite productivity tools, helping me with my research on various topics in addition to providing me with multiple perspectives on a topic.
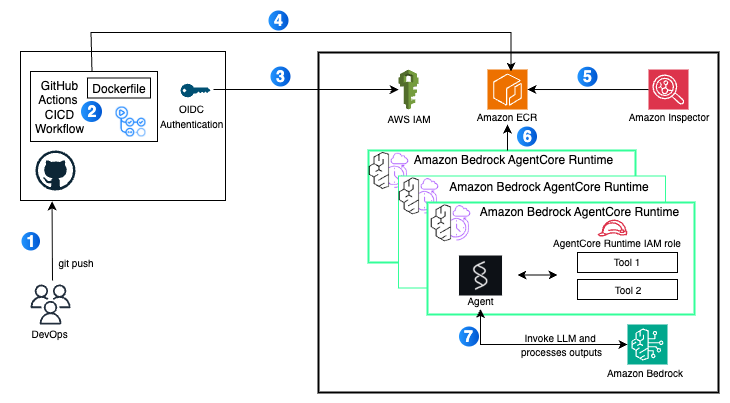
  • Deploy AI agents on Amazon Bedrock AgentCore using GitHub Actions – Last year we announced Amazon Bedrock AgentCore, a flexible service that helps you seamlessly create and manage AI agents across different frameworks and models, whether hosted on Amazon Bedrock or other environments. Learn how to use a GitHub Actions workflow to automate the deployment of AI agents on AgentCore Runtime. This approach delivers a scalable solution with enterprise-level security controls, providing complete continuous integration and delivery (CI/CD) automation.

Upcoming AWS events
Join us January 28 or 29 (depending on your time zone) for Best of AWS re:Invent, a free virtual event where we bring you the most impactful announcements and top sessions from AWS re:Invent. Jeff Barr, AWS VP and Chief Evangelist, will share his highlights during the opening session.

There is still time until January 21 to compete for $250,000 in prizes and AWS credits in the Global 10,000 AIdeas Competition (yes, the second letter is an I as in Idea, not an L as in like). No code required yet: simply submit your idea, and if you’re selected as a semifinalist, you’ll build your app using Kiro within AWS Free Tier limits. Beyond the cash prizes and potential featured placement at AWS re:Invent 2026, you’ll gain hands-on experience with next-generation AI tools and connect with innovators globally.

Earlier this month, the 2026 application for the Community Builders program launched. The application is open until January 21st, midnight PST so here’s your last chance to ensure that you don’t miss out.

If you’re interested in these opportunities, join the AWS Builder Center to learn with builders in the AWS community.

With that, I close one of my most meaningful chapters here at AWS. It’s been an absolute pleasure to write for you and I thank you for taking the time to read the work that my team and I pour our absolute hearts into. I’ve grown from the close collaborations with the launch teams and the feedback from all of you. The Sub-Sahara Africa (SSA) community has grown significantly, and I want to dedicate more time focused on this community, I’m still at AWS and I look forward to meeting at an event near you!

Check back next Monday for another Weekly Roundup!

– Veliswa Boya

Amazon EC2 X8i instances powered by custom Intel Xeon 6 processors are generally available for memory-intensive workloads

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-ec2-x8i-instances-powered-by-custom-intel-xeon-6-processors-are-generally-available-for-memory-intensive-workloads/

Since a preview launch at AWS re:Invent 2025, we’re announcing the general availability of new memory-optimized Amazon Elastic Compute Cloud (Amazon EC2) X8i instances. These instances are powered by custom Intel Xeon 6 processors with a sustained all-core turbo frequency of 3.9 GHz, available only on AWS. These SAP certified instances deliver the highest performance and fastest memory bandwidth among comparable Intel processors in the cloud.

X8i instances are ideal for memory-intensive workloads including in-memory databases such as SAP HANA, traditional large-scale databases, data analytics, and electronic design automation (EDA), which require high compute performance and a large memory footprint.

These instances provide 1.5 times more memory capacity (up to 6 TB), and 3.4 times more memory bandwidth compared to previous generation X2i instances. These instances offer up to 43% higher performance compared to X2i instances, with higher gains on some of the real-world workloads. They deliver up to 50% higher SAP Application Performance Standard (SAPS) performance, up to 47% faster PostgreSQL performance, up to 88% faster Memcached performance, and up to 46% faster AI inference performance.

During the preview, customers like RISE with SAP utilized up to 6 TB of memory capacity with 50% higher compute performance compared to X2i instances. This enabled faster transaction processing and improved query response times for SAP HANA workloads. Orion reduced the number of active cores on X8i instances compared to X2idn instances while maintaining performance thresholds, cutting SQL Server licensing costs by 50%.

X8i instances
X8i instances are available in 14 sizes including three larger instance sizes (48xlarge, 64xlarge, and 96xlarge), so you can choose the right size for your application to scale up, and two bare metal sizes (metal-48xl and metal-96xl) to deploy workloads that benefit from direct access to physical resources. X8i instances feature up to 100 Gbps of network bandwidth with support for the Elastic Fabric Adapter (EFA) and up to 80 Gbps of throughput to Amazon Elastic Block Store (Amazon EBS).

Here are the specs for X8i instances:

Instance name vCPUs Memory
(GiB)
Network bandwidth (Gbps) EBS bandwidth (Gbps)
x8i.large 2 32 Up to 12.5 Up to 10
x8i.xlarge 4 64 Up to 12.5 Up to 10
x8i.2xlarge 8 128 Up to 15 Up to 10
x8i.4xlarge 16 256 Up to 15 Up to 10
x8i.8xlarge 32 512 15 10
x8i.12xlarge 48 768 22.5 15
x8i.16xlarge 64 1,024 30 20
x8i.24xlarge 96 1,536 40 30
x8i.32xlarge 128 2,048 50 40
x8i.48xlarge 192 3,072 75 60
x8i.64xlarge 256 4,096 80 70
x8i.96xlarge 384 6,144 100 80
x8i.metal-48xl 192 3,072 75 60
x8i.metal-96xl 384 6,144 100 80

X8i instances support the instance bandwidth configuration (IBC) feature like other eighth-generation instance types, offering flexibility to allocate resources between network and EBS bandwidth. You can scale network or EBS bandwidth by up to 25%, improving database performance, query processing speeds, and logging efficiency. These instances also use sixth-generation AWS Nitro cards, which offload CPU virtualization, storage, and networking functions to dedicated hardware and software, enhancing performance and security for your workloads.

Now available
Amazon EC2 X8i instances are now available in US East (N. Virginia), US East (Ohio), US West (Oregon), and Europe (Frankfurt) AWS Regions. For Regional availability and a future roadmap, search the instance type in the CloudFormation resources tab of AWS Capabilities by Region.

You can purchase these instances as On-Demand Instances, Savings Plan, and Spot Instances. To learn more, visit the Amazon EC2 Pricing page.

Give X8i instances a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 X8i instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

Happy New Year! AWS Weekly Roundup: 10,000 AIdeas Competition, Amazon EC2, Amazon ECS Managed Instances and more (January 5, 2026)

Post Syndicated from Prasad Rao original https://aws.amazon.com/blogs/aws/happy-new-year-aws-weekly-roundup-10000-aideas-competition-amazon-ec2-amazon-ecs-managed-instances-and-more-january-5-2026/

Happy New Year! I hope the holidays gave you time to recharge and spend time with your loved ones.

Like every year, I took a few weeks off after AWS re:Invent to rest and plan ahead. I used some of that downtime to plan the next cohort for Become a Solutions Architect (BeSA). BeSA is a free mentoring program that I, along with a few other Amazon Web Services (AWS) employees, volunteer to host as a way to help people excel in their cloud and AI careers. We’re kicking off a 6-week cohort on “Agentic AI on AWS” starting February 21, 2026. Visit the BeSA website to learn more.

There is still time to submit your idea for the Global 10,000 AIdeas Competition and compete for $250,000 in cash prizes, AWS credits, and recognition, including potential featured placement at AWS re:Invent 2026 and across AWS channels.

You will gain hands-on experience with next-generation AI development tools, connect with innovators globally, and access technical enablement through biweekly workshops, AWS User Groups, and AWS Builder Center resources.

The deadline is January 21, 2026, and no code is required yet. If you’re selected as a semifinalist, you’ll build your app then. Your finished app needs to use Kiro for at least part of development, stay within AWS Free Tier limits, and be completely original and not yet published.

If you haven’t yet caught up with all the new releases and announcements from AWS re:Invent 2025, check out our top announcements post or watch the keynotes, innovation talks, and breakout sessions on-demand.

Launches from the last few weeks
I’d like to highlight some launches that got my attention since our last Week in Review on December 15, 2025:

  • Amazon EC2 M8gn and M8gb instances – New M8gn and M8gb instances are powered by AWS Graviton4 processors to deliver up to 30% better compute performance than AWS Graviton3 processors. M8gn instances feature the latest 6th generation AWS Nitro Cards, and offer up to 600 Gbps network bandwidth, the highest network bandwidth among network-optimized EC2 instances. M8gb offer up to 150 Gbps of Amazon EBS bandwidth to provide higher EBS performance compared to same-sized equivalent Graviton4-based instances.
  • AWS Direct Connect supports resilience testing with AWS Fault Injection Service – You can now use AWS Fault Injection Service to test how your applications handle Direct Connect Border Gateway Protocol (BGP) failover in a controlled environment. For example, you can validate that traffic routes to redundant virtual interfaces when a primary virtual interface’s BGP session is disrupted and your applications continue to function as expected.
  • New AWS Security Hub controls in AWS Control Tower – AWS Control Tower now supports 176 additional Security Hub controls in the Control Catalog, covering use cases including security, cost, durability, and operations. With this launch, you can search, discover, enable, and manage these controls directly from AWS Control Tower to govern additional use cases across your multi-account environment.
  • AWS Transform supports network conversion for hybrid data center migrations – You can now use AWS Transform for VMware to automatically convert networks from hybrid data centers. This removes manual network mapping for environments running both VMware and other workloads. The service analyzes VLANs and IP ranges across all exported source networks and maps them to AWS constructs such as virtual private clouds (VPCs), subnets, and security groups.
  • NVIDIA Nemotron 3 Nano available on Amazon Bedrock – Amazon Bedrock now supports NVIDIA Nemotron 3 Nano 30B A3B model, NVIDIA’s latest breakthrough in efficient language modeling that delivers high reasoning performance, built-in tool calling support, and extended context processing with 256K token context window.
  • Amazon EC2 supports Availability Zone ID across its APIs – You can specify the Availability Zone ID (AZ ID) parameter directly in your Amazon EC2 APIs to guarantee consistent placement of resources. AZ IDs are consistent and static identifiers that represent the same physical location across all AWS accounts, helping you optimize resource placement. Prior to this launch, you had to use an AZ name while creating a resource, but these names could map to different physical locations. This mapping made it difficult to ensure resources were always co-located, especially when operating with multiple accounts.
  • Amazon ECS Managed Instances supports Amazon EC2 Spot Instances – Amazon ECS Managed Instances now supports Amazon EC2 Spot Instances, extending the range of capabilities available with AWS managed infrastructure. You can use spare EC2 capacity at up to 90% discount compared to On-Demand prices for fault-tolerant workloads in Amazon ECS Managed Instances.

See AWS What’s New for more launch news that I haven’t covered here. That’s all for this week. Check back next Monday for another Weekly Roundup!

Here’s to a fantastic start to 2026. Happy building!

– Prasad

Modernize Apache Spark workflows using Spark Connect on Amazon EMR on Amazon EC2

Post Syndicated from Philippe Wanner original https://aws.amazon.com/blogs/big-data/modernize-apache-spark-workflows-using-spark-connect-on-amazon-emr-on-amazon-ec2/

Apache Spark Connect, introduced in Spark 3.4, enhances the Spark ecosystem by offering a client-server architecture that separates the Spark runtime from the client application. Spark Connect enables more flexible and efficient interactions with Spark clusters, particularly in scenarios where direct access to cluster resources is limited or impractical.

A key use case for Spark Connect on Amazon EMR is to be able to connect directly from your local development environments to Amazon EMR clusters. By using this decoupled approach, you can write and test Spark code on your laptop while using Amazon EMR clusters for execution. This capability reduces development time and simplifies data processing with Spark on Amazon EMR.

In this post, we demonstrate how to implement Apache Spark Connect on Amazon EMR on Amazon Elastic Compute Cloud (Amazon EC2) to build decoupled data processing applications. We show how to set up and configure Spark Connect securely, so you can develop and test Spark applications locally while executing them on remote Amazon EMR clusters.

Solution architecture

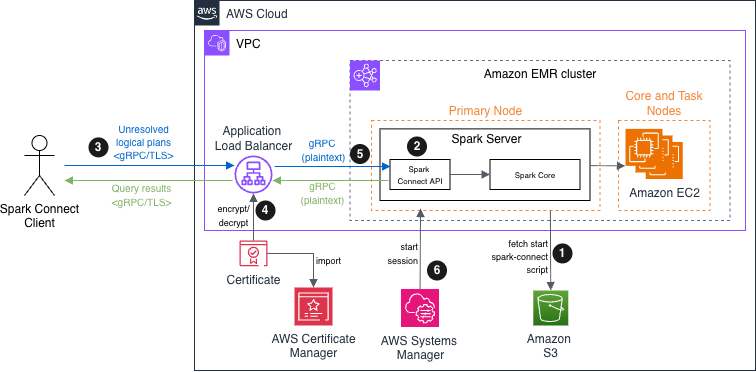
The architecture centers on an Amazon EMR cluster with two node types. The primary node hosts both the Spark Connect API endpoint and Spark Core components, serving as the gateway for client connections. The core node provides additional compute capacity for distributed processing. Although this solution demonstrates the architecture with two nodes for simplicity, it scales to support multiple core and task nodes based on workload requirements.

In Apache Spark Connect version 4.x, TLS/SSL network encryption is not inherently supported. We show you how to implement secure communications by deploying an Amazon EMR cluster with Spark Connect on Amazon EC2 using an Application Load Balancer (ALB) with TLS termination as the secure interface. This approach enables encrypted data transmission between Spark Connect clients and Amazon Virtual Private Cloud (Amazon VPC) resources.

The operational flow is as follows:

  1. Bootstrap script – During Amazon EMR initialization, the primary node fetches and executes the start-spark-connect.sh file from Amazon Simple Storage Service (Amazon S3). This script starts the Spark Connect server.
  2. Server availability – When the bootstrap process is complete, the Spark Server enters a waiting state, ready to accept incoming connections. The Spark Connect API endpoint becomes available on the configured port (typically 15002), listening for gRPC connection from remote clients.
  3. Client interaction – Spark Connect clients can establish secure connections to an Application Load Balancer. These clients translate DataFrame operations into unresolved logical query plans, encode these plans using protocol buffers, and send them to the Spark Connect API using gRPC.
  4. Encryption in transit – The Application Load Balancer receives incoming gRPC or HTTPS traffic, performs TLS termination (decrypting the traffic), and forwards the requests to the primary node. The certificate is stored in AWS Certificate Manager (ACM).
  5. Request processing – The Spark Connect API receives the unresolved logical plans, translates them into Spark’s built-in logical plan operators, passes them to Spark Core for optimization and execution, and streams results back to the client as Apache Arrow-encoded row batches.
  6. (Optional) Operational access – Administrators can securely connect to both primary and core nodes through Session Manager, a capability of AWS Systems Manager, enabling troubleshooting and maintenance without exposing SSH ports or managing key pairs.

The following diagram depicts the architecture of this post’s demonstration for submitting Spark unresolved logical plans to EMR clusters using Spark Connect.

Apache Spark Connect on Amazon EMR solution architecture diagram

Apache Spark Connect on Amazon EMR solution architecture diagram

Prerequisites

To proceed with this post, ensure you have the following:

Implementation steps

In this recipe, through AWS CLI commands, you will:

  1. Prepare the bootstrap script, a bash script starting Spark Connect on Amazon EMR.
  2. Set up the permissions for Amazon EMR to provision resources and perform service-level actions with other AWS services.
  3. Create the Amazon EMR cluster with these associated roles and permissions and eventually attach the prepared script as a bootstrap action.
  4. Deploy the Application Load Balancer and certificate with ACM secure data in transit over the internet.
  5. Modify the primary node’s security group to allow Spark Connect clients to connect.
  6. Connect with a test application connecting the client to Spark Connect server.

Prepare the bootstrap script

To prepare the bootstrap script, follow these steps:

  1. Create an Amazon S3 bucket to host the bootstrap bash script:
    REGION=
    BUCKET_NAME=
    aws s3api create-bucket \
       --bucket $BUCKET_NAME \ 
       --region $REGION \
       --create-bucket-configuration LocationConstraint=$REGION

  2. Open your preferred text editor, add the following commands in a new file with a name such start-spark-connect.sh. If the script runs on the primary node, it starts Spark Connect server. If it runs on a task or core node, it does nothing:
    #!/bin/bash
    if grep isMaster /mnt/var/lib/info/instance.json | grep false;
    then
        echo "This is not master node, do nothing."
        exit 0
    fi
    echo "This is master, continuing to execute script"
    SPARK_HOME=/usr/lib/spark
    SPARK_VERSION=$(spark-submit --version 2>&1 | grep "version" | head -1 | awk '{print $NF}' | grep -oE '[0-9]+\.[0-9]+\.[0-9]+')
    SCALA_VERSION=$(spark-submit --version 2>&1 | grep -o "Scala version [0-9.]*" | awk '{print $3}' | grep -oE '[0-9]+\.[0-9]+')
    echo "Spark version ${SPARK_VERSION} is installed under ${SPARK_HOME} running with scala version ${SCALA_VERSION}"
    sudo "${SPARK_HOME}"/sbin/start-connect-server.sh --packages org.apache.spark:spark-connect_"${SCALA_VERSION}:${SPARK_VERSION}"

  3. Upload the script into the bucket created in step 1:
    aws s3 cp start-spark-connect.sh s3://$BUCKET_NAME
    

Set up the permissions

Before creating the cluster, you must create the service role, and instance profile. A service role is an IAM role that Amazon EMR assumes to provision resources and perform service-level actions with other AWS services. An EC2 instance profile for Amazon EMR assigns a role to every EC2 instance in a cluster. The instance profile must specify a role that can access the resources for your bootstrap action.

  1. Create the IAM role:
    aws iam create-role \
    --role-name AmazonEMR-ServiceRole-SparkConnectDemo \
    --assume-role-policy-document '{
    	"Version": "2012-10-17",
    	"Statement": [{
    		"Effect": "Allow",
    		"Principal": {"Service": "elasticmapreduce.amazonaws.com"},
    		"Action": "sts:AssumeRole"
    		}]
    }'
    

  2. Attach the necessary managed policies to the service role to allow Amazon EMR to manage the underlying services Amazon EC2 and Amazon S3 on your behalf and optionally grant an instance to interact with Systems Manager:
    aws iam attach-role-policy \
    --role-name AmazonEMR-ServiceRole-SparkConnectDemo \
    --policy-arn arn:aws:iam::aws:policy/service-role/AmazonEMRServicePolicy_v2
    
    aws iam attach-role-policy \
    --role-name AmazonEMR-ServiceRole-SparkConnectDemo \
    --policy-arn arn:aws:iam::aws:policy/AmazonSSMManagedInstanceCore
    
    aws iam attach-role-policy \
    --role-name AmazonEMR-ServiceRole-SparkConnectDemo \
    --policy-arn arn:aws:iam::aws:policy/service-role/AmazonElasticMapReduceRole
    

  3. Create an Amazon EMR instance role to grant permissions to EC2 instances to interact with Amazon S3 or other AWS services:
    aws iam create-role \
    --role-name EMR_EC2_SparkClusterNodesRole \
    --assume-role-policy-document '{
    "Version": "2012-10-17",
    "Statement": [{
       "Effect": "Allow",
       "Principal": {"Service": "ec2.amazonaws.com"},
       "Action": "sts:AssumeRole"
       }]
    }'
    

  4. To allow the primary instance to read from Amazon S3, attach the AmazonS3ReadOnlyAccess policy to the Amazon EMR instance role. For production environments, this access policy should be reviewed and replaced with a custom policy following the principle of least privilege, granting only the specific permissions needed for your use case:
    aws iam attach-role-policy \
    --role-name EMR_EC2_SparkClusterNodesRole \
    --policy-arn arn:aws:iam::aws:policy/AmazonS3ReadOnlyAccess
    

  5. Attaching AmazonSSMManagedInstanceCore policy enables the instances to use core Systems Manager features, such as Session Manager, and Amazon CloudWatch:
    aws iam attach-role-policy \
    --role-name EMR_EC2_SparkClusterNodesRole \
    --policy-arn arn:aws:iam::aws:policy/AmazonSSMManagedInstanceCore
    

  6. To pass the EMR_EC2_SparkClusterInstanceProfile IAM role information to the EC2 instances when they start, create the Amazon EMR EC2 instance profile:
    aws iam create-instance-profile \
    --instance-profile-name EMR_EC2_SparkClusterInstanceProfile
    

  7. Attach the role EMR_EC2_SparkClusterNodesRole created in step 3 to the newly instance profile:
    aws iam add-role-to-instance-profile \
    --instance-profile-name EMR_EC2_SparkClusterInstanceProfile \
    --role-name EMR_EC2_SparkClusterNodesRole
    

Create the Amazon EMR cluster

To create the Amazon EMR cluster, follow these steps:

  1. Set the environment variables, where your EMR cluster and load-balancer must be deployed:
    VPC_ID=<vpc-emr-and-alb>
    EMR_PRI_SB_ID_1=<emr-private-subnet-id-az1>
    ALB_PUB_SB_ID_1=<alb-public-subnet-id-az1>
    ALB_PUB_SB_ID_2=<alb-public-subnet-id-az2>
    

  2. Create the EMR cluster with the latest Amazon EMR release. Replace the placeholder value with your actual S3 bucket name where the bootstrap action script is stored:
    CLUSTER_ID=$(aws emr create-cluster \
    --name "Spark Connect cluster demo" \
    --applications Name=Spark \
    --release-label emr-7.9.0 \
    --service-role AmazonEMR-ServiceRole-SparkConnectDemo \
    --ec2-attributes InstanceProfile=EMR_EC2_SparkClusterInstanceProfile,SubnetId=$EMR_PRI_SB_ID_1 \
    --instance-groups InstanceGroupType=MASTER,InstanceCount=1,InstanceType=m5.xlarge InstanceGroupType=CORE,InstanceCount=1,InstanceType=m5.xlarge \
    --bootstrap-actions Path="s3://$BUCKET_NAME/start-spark-connect.sh" \
    --query 'ClusterId' --output text)
    echo CLUSTER_ID="$CLUSTER_ID"
    

    To modify primary node’s security group to allow Systems Manager to start a session.

  3. Get the primary node’s security group identifier. Record the identifier because you’ll need it for subsequent configuration steps in which primary-node-security-group-id is mentioned:
    PRIMARY_NODE_SG=$(aws emr describe-cluster \
    --cluster-id $CLUSTER_ID \
    --query 'Cluster.Ec2InstanceAttributes.EmrManagedMasterSecurityGroup' \
    --output text)
    echo PRIMARY_NODE_SG=$PRIMARY_NODE_SG
    

  4. Find the EC2 instance connect prefix list ID for your Region. You can use the EC2_INSTANCE_CONNECT filter with the describe-managed-prefix-lists command. Using a managed prefix list provides a dynamic security configuration to authorize Systems Manager EC2 instances to connect the primary and core nodes by SSH:
    IC_PREFIX_LIST=$(aws ec2 describe-managed-prefix-lists \
    --filters Name=prefix-list-name,Values=com.amazonaws.$REGION.ec2-instance-connect \
    --query 'PrefixLists[0].PrefixListId' \
    --output text)
    echo IC_PREFIX_LIST=$IC_PREFIX_LIST
    

  5. Modify the primary node security group inbound rules to allow SSH access (port 22) to the EMR cluster’s primary node from resources that are part of the specified Instance Connect service contained in the prefix list:
    aws ec2 authorize-security-group-ingress \
    --region $REGION \
    --group-id $PRIMARY_NODE_SG \
    --ip-permissions "[{\"IpProtocol\":\"tcp\",\"FromPort\":22,\"ToPort\":22,\"PrefixListIds\":[{\"PrefixListId\":\"$IC_PREFIX_LIST\"}]}]"
    

Optionally, you can repeat the preceding steps 1–3 for the core (and tasks) cluster’s nodes to allow Amazon EC2 Instance Connect to access the EC2 instance through SSH.

Deploy the Application Load Balancer and certificate

To deploy the Application Load Balancer and certificate, follow these steps:

  1. Create a load balancer’s security group:
    ALB_SG_ID=$(aws ec2 create-security-group \
    --group-name spark-connect-alb-sg \
    --description "Security group for Spark Connect ALB" \
    --region $REGION \
    --vpc-id $VPC_ID \
    --query 'GroupId' \
    --output text)
    

  2. Add rule to accept TCP traffic from a trusted IP on port 443. We recommend that you use the local development machine’s IP address. You can check your current public IP address here: https://checkip.amazonaws.com:
    aws ec2 authorize-security-group-ingress \
    --group-id $ALB_SG_ID \
    --protocol tcp \
    --port 443 \
    --cidr <replace-with-trusted-IP>/32
    

  3. Create a new target group with gRPC protocol, which targets the Spark Connect server instance and the port the server is listening to:
    ALB_TG_ARN=$(aws elbv2 create-target-group \
    --name spark-connect-tg \
    --protocol HTTP \
    --protocol-version GRPC \
    --port 15002 \
    --target-type instance \
    --health-check-enabled \
    --health-check-protocol HTTP \
    --health-check-path / \
    --vpc-id $VPC_ID \
    --query 'TargetGroups[0].TargetGroupArn' \
    --output text)
    echo "ALB TG created (ARN)=$ALB_TG_ARN"
    

  4. Create the Application Load Balancer:
    ALB_ARN=$(aws elbv2 create-load-balancer \
    --name spark-connect-alb \
    --type application \
    --scheme internet-facing \
    --subnets $ALB_PUB_SB_ID_1 $ALB_PUB_SB_ID_2 \
    --security-groups $ALB_SG_ID \
    --query 'LoadBalancers[0].LoadBalancerArn' \
    --output text)
    echo "ALB created (ARN)=$ALB_ARN"
    

  5. Get the load balancer DNS name:
    ALB_DNS=$(aws elbv2 describe-load-balancers \
    --load-balancer-arns $ALB_ARN \
    --query 'LoadBalancers[0].DNSName' \
    --output text)
    echo "ALB DNS=$ALB_DNS"
    

  6. Retrieve the Amazon EMR primary node ID:
    PRIMARY_NODE_ID=$(aws emr list-instances --cluster-id $CLUSTER_ID --instance-group-types MASTER --query 'Instances[0].Ec2InstanceId' --output text)
    echo PRIMARY_NODE_ID=$PRIMARY_NODE_ID
    

  7. (Optional) To encrypt and decrypt the traffic, the load balancer needs a certificate. You can skip this step if you already have a trusted certificate in ACM. Otherwise, create a self-signed certificate:
    PRIVATE_KEY_PATH=./sc-private-key.key
    CERTIFICATE_PATH=./sc-certificate.cert
    sudo openssl req -x509 -nodes -days 365 -newkey rsa:2048 -keyout $PRIVATE_KEY_PATH -out $CERTIFICATE_PATH -subj "/CN=$ALB_DNS"
    

  8. Upload to ACM:
    ACM_CERT_ARN=$(aws acm import-certificate \
    --certificate fileb://$CERTIFICATE_PATH \
    --private-key fileb://$PRIVATE_KEY_PATH \
    --region $REGION \
    --query CertificateArn \
    --output text)
    echo "Certificate created (ARN)=$ACM_CERT_ARN"
    

  9. Create the load balancer listener:
    ALB_LISTENER_ARN=$(aws elbv2 create-listener \
    --load-balancer-arn $ALB_ARN \
    --protocol HTTPS \
    --port 443 \
    --certificates CertificateArn=$ACM_CERT_ARN \
    --ssl-policy ELBSecurityPolicy-TLS13-1-2-2021-06 \
    --default-actions Type=forward,TargetGroupArn=$ALB_TG_ARN \
    --region $REGION \
    --query 'Listeners[0].ListenerArn' \
    --output text)
    echo "ALB listener created (ARN)=$ALB_LISTENER_ARN"
    

  10. After the listener has been provisioned, register the primary node to the target group:
    aws elbv2 register-targets \
    --target-group-arn $ALB_TG_ARN \
    --targets Id=$PRIMARY_NODE_ID
    

Modify the primary node’s security group to allow Spark Connect clients to connect

To connect to Spark Connect, amend only the primary security group. Add an inbound rule to the primary’s node security group to accept Spark Connect TCP connection on port 15002 from your chosen trusted IP address:

aws ec2 authorize-security-group-ingress \
--group-id $PRIMARY_NODE_SG \
--protocol tcp \
--port 15002 \
--source-group $ALB_SG_ID

Connect with a test application

This example demonstrates that a client running a newer Spark version (4.0.1) can successfully connect to an older Spark version on the Amazon EMR cluster (3.5.5), showcasing Spark Connect’s version compatibility feature. This version combination is for demonstration only. Running older versions might pose security risks in production environments.

To test the client-to-server connection, we provide the following test Python application. We recommend that you create and activate a Python virtual environment (venv) before installing the packages. This helps isolate the dependencies for this specific project and prevents conflicts with other Python projects. To install packages, run the following command:

pip install pyspark-client==4.0.1

In your integrated development environment (IDE), copy and paste the following code, replace the placeholder, and invoke it. The code creates a Spark DataFrame containing two rows and it shows its data:

from pyspark.sql import SparkSession
import os
os.environ['GRPC_DEFAULT_SSL_ROOTS_FILE_PATH'] = os.path.expanduser('sc-certificate.cert')
spark = SparkSession.builder \
    .remote("sc://:443/;use_ssl=true") \
    .config('spark.sql.execution.pandas.inferPandasDictAsMap', True) \
    .config('spark.sql.pyspark.legacy.inferMapTypeFromFirstPair.enabled', True) \
    .getOrCreate()
spark.createDataFrame([("sue", 32),("li", 3)],["first_name", "age"]).show()

The following shows the application output:

+----------+---+
|first_name|age|
+----------+---+
|       sue| 32|
|        li|  3|
+----------+---+

Clean up

When you no longer need the cluster, release the following resources to stop incurring charges:

  1. Delete the Application Load Balancer listener, target group, and the load balancer.
  2. Delete the ACM certificate.
  3. Delete the load balancer and Amazon EMR node security groups.
  4. Terminate the EMR cluster.
  5. Empty the Amazon S3 bucket and delete it.
  6. Remove AmazonEMR-ServiceRole-SparkConnectDemo and EMR_EC2_SparkClusterNodesRole roles and EMR_EC2_SparkClusterInstanceProfile instance profile.

Considerations

Security considerations with Spark Connect:

  • Private subnet deployment – Keep EMR clusters in private subnets with no direct internet access, using NAT gateways for outbound connectivity only.
  • Access logging and monitoring – Enable VPC Flow Logs, AWS CloudTrail, and bastion host access logs for audit trails and security monitoring.
  • Security group restrictions – Configure security groups to allow Spark Connect port (15002) access only from bastion host or specific IP ranges.

Conclusion

In this post, we showed how you can adopt modern development workflows and debug Spark applications from local IDEs or notebooks, so you can step through code execution. With Spark Connect’s client-server architecture, the Spark cluster can run on a different version than the client applications, so operations teams can perform infrastructure upgrades and patches independently.

As the cluster operators gain experience, they can customize the bootstrap actions and add steps to process data. Consider exploring Amazon Managed Workflows for Apache Airflow (MWAA) for orchestrating your data pipeline.


About the authors

Philippe Wanner

Philippe Wanner

Philippe is EMEA Tech Lead at AWS. His role is to accelerate the digital transformation for large organizations. His current focus is in a multidisciplinary area involving business transformation, technical strategy, and distributed systems.

Ege Oguzman

Ege Oguzman

Ege is a Software Development Engineer at AWS, and previously he was a Solutions Architect in the public sector. As a builder and cloud enthusiast, he specializes in distributed systems and dedicates his time to infrastructure development and helping organizations build solutions on AWS.

Cryptomining campaign targeting Amazon EC2 and Amazon ECS

Post Syndicated from Kyle Koeller original https://aws.amazon.com/blogs/security/cryptomining-campaign-targeting-amazon-ec2-and-amazon-ecs/

Amazon GuardDuty and our automated security monitoring systems identified an ongoing cryptocurrency (crypto) mining campaign beginning on November 2, 2025. The operation uses compromised AWS Identity and Access Management (IAM) credentials to target Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Compute Cloud (Amazon EC2). GuardDuty Extended Threat Detection was able to correlate signals across these data sources to raise a critical severity attack sequence finding. Using the massive, advanced threat intelligence capability and existing detection mechanisms of Amazon Web Services (AWS), GuardDuty proactively identified this ongoing campaign and quickly alerted customers to the threat. AWS is sharing relevant findings and mitigation guidance to help customers take appropriate action on this ongoing campaign.

It’s important to note that these actions don’t take advantage of a vulnerability within an AWS service but rather require valid credentials that an unauthorized user uses in an unintended way. Although these actions occur in the customer domain of the shared responsibility model, AWS recommends steps that customers can use to detect, prevent, or reduce the impact of such activity.

Understanding the crypto mining campaign

The recently detected crypto mining campaign employed a novel persistence technique designed to disrupt incident response and extend mining operations. The ongoing campaign was originally identified when GuardDuty security engineers discovered similar attack techniques being used across multiple AWS customer accounts, indicating a coordinated campaign targeting customers using compromised IAM credentials.

Operating from an external hosting provider, the threat actor quickly enumerated Amazon EC2 service quotas and IAM permissions before deploying crypto mining resources across Amazon EC2 and Amazon ECS. Within 10 minutes of the threat actor gaining initial access, crypto miners were operational.

A key technique observed in this attack was the use of ModifyInstanceAttribute with disable API termination set to true, forcing victims to re-enable API termination before deleting the impacted resources. Disabling instance termination protection adds an additional consideration for incident responders and can disrupt automated remediation controls. The threat actor’s scripted use of multiple compute services, in combination with emerging persistence techniques, represents an advancement in crypto mining persistence methodologies that security teams should be aware of.

The multiple detection capabilities of GuardDuty successfully identified the malicious activity through EC2 domain/IP threat intelligence, anomaly detection, and Extended Threat Detection EC2 attack sequences. GuardDuty Extended Threat Detection was able to correlate signals as an AttackSequence:EC2/CompromisedInstanceGroup finding.

Indicators of compromise (IoCs)

Security teams should monitor for the following indicators to identify this crypto mining campaign. Threat actors frequently modify their tactics and techniques, so these indicators might evolve over time:

  • Malicious container image – The Docker Hub image yenik65958/secret, created on October 29, 2025, with over 100,000 pulls, was used to deploy crypto miners to containerized environments. This malicious image contained a SBRMiner-MULTI binary for crypto mining. This specific image has been taken down from Docker Hub, but threat actors might deploy similar images under different names.
  • Automation and tooling – AWS SDK for Python (Boto3) user agent patterns indicating Python-based automation scripts were used across the entire attack chain.
  • Crypto mining domains: asia[.]rplant[.]xyz, eu[.]rplant[.]xyz, and na[.]rplant[.]xyz.
  • Infrastructure naming patterns – Auto scaling groups followed specific naming conventions: SPOT-us-east-1-G*-* for spot instances and OD-us-east-1-G*-* for on-demand instances, where G indicates the group number.

Attack chain analysis

The crypto mining campaign followed a systematic attack progression across multiple phases. Sensitive fields in this post were given fictitious values to protect personally identifiable information (PII).

Cryptocurrency Mining Campaign Diagram

Figure 1: Cryptocurrency mining campaign diagram

Initial access, discovery, and attack preparation

The attack began with compromised IAM user credentials possessing admin-like privileges from an anomalous network and location, triggering GuardDuty anomaly detection findings. During the discovery phase, the attacker systematically probed customer AWS environments to understand what resources they could deploy. They checked Amazon EC2 service quotas (GetServiceQuota) to determine how many instances they could launch, then tested their permissions by calling the RunInstances API multiple times with the DryRun flag enabled.

The DryRun flag was a deliberate reconnaissance tactic that allowed the actor to validate their IAM permissions without actually launching instances, avoiding costs and reducing their detection footprint. This technique demonstrates the threat actor was validating their ability to deploy crypto mining infrastructure before acting. Organizations that don’t typically use DryRun flags in their environments should consider monitoring for this API pattern as an early warning indicator of compromise. AWS CloudTrail logs can be used with Amazon CloudWatch alarms, Amazon EventBridge, or your third-party tooling to alert on these suspicious API patterns.

The threat actor called two APIs to create IAM roles as part of their attack infrastructure: CreateServiceLinkedRole to create a role for auto scaling groups and CreateRole to create a role for AWS Lambda. They then attached the AWSLambdaBasicExecutionRole policy to the Lambda role. These two roles were integral to the impact and persistence stages of the attack.

Amazon ECS impact

The threat actor first created dozens of ECS clusters across the environment, sometimes exceeding 50 ECS clusters in a single attack. They then called RegisterTaskDefinition with a malicious Docker Hub image yenik65958/secret:user. With the same string used for the cluster creation, the actor then created a service, using the task definition to initiate crypto mining on ECS AWS Fargate nodes. The following is an example of API request parameters for RegisterTaskDefinition with a maximum CPU allocation of 16,384 units.

{   
    "dryrun": false,   
    "requiresCompatibilities": ["FARGATE"],   
    "cpu": 16384,   
    "containerDefinitions": [     
        {       
            "name": "a1b2c3d4e5",       
            "image": "yenik65958/secret:user",       
            "cpu": 0,       
            "command": []     
        }   
    ],   
    "networkMode": "awsvpc",   
    "family": "a1b2c3d4e5",   
    "memory": 32768 
}

Using this task definition, the threat actor called CreateService to launch ECS Fargate tasks with a desired count of 10.

{   
    "dryrun": false,   
    "capacityProviderStrategy": [     
        {       
            "capacityProvider": "FARGATE",       
            "weight": 1,       
            "base": 0     
        },     
        {       
            "capacityProvider": "FARGATE_SPOT",       
            "weight": 1,       
            "base": 0     
        }   
    ],   
    "desiredCount": 10 
}

Figure 2: Contents of the cryptocurrency mining script within the malicious image

Figure 2: Contents of the cryptocurrency mining script within the malicious image

The malicious image (yenik65958/secret:user) was configured to execute run.sh after it has been deployed. run.sh runs randomvirel mining algorithm with the mining pools: asia|eu|na[.]rplant[.]xyz:17155. The flag nproc --all indicates that the script should use all processor cores.

Amazon EC2 impact

The actor created two launch templates (CreateLaunchTemplate) and 14 auto scaling groups (CreateAutoScalingGroup) configured with aggressive scaling parameters, including a maximum size of 999 instances and desired capacity of 20. The following example of request parameters from CreateLaunchTemplate shows the UserData was supplied, instructing the instances to begin crypto mining.

{   
    "CreateLaunchTemplateRequest": {       
        "LaunchTemplateName": "T-us-east-1-a1b2",       
        "LaunchTemplateData": {           
            "UserData": "<sensitiveDataRemoved>",           
            "ImageId": "ami-1234567890abcdef0",           
            "InstanceType": "c6a.4xlarge"       
        },       
        "ClientToken": "a1b2c3d4-5678-90ab-cdef-EXAMPLE11111"   
    } 
}

The threat actor created auto scaling groups using both Spot and On-Demand Instances to make use of both Amazon EC2 service quotas and maximize resource consumption.

Spot Instance groups:

  • Targeted high performance GPU and machine learning (ML) instances (g4dn, g5, g5, p3, p4d, inf1)
  • Configured with 0% on-demand allocation and capacity-optimized strategy
  • Set to scale from 20 to 999 instances

On-Demand Instance groups:

  • Targeted compute, memory, and general-purpose instances (c5, c6i, r5, r5n, m5a, m5, m5n).
  • Configured with 100% on-demand allocation
  • Also set to scale from 20 to 999 instances

After exhausting auto scaling quotas, the actor directly launched additional EC2 instances using RunInstances to consume the remaining EC2 instance quota.

Persistence

An interesting technique observed in this campaign was the threat actor’s use of ModifyInstanceAttribute across all launched EC2 instances to disable API termination. Although instance termination protection prevents accidental termination of the instance, it adds an additional consideration for incident response capabilities and can disrupt automated remediation controls. The following example shows request parameters for the API ModifyInstanceAttribute.

{     
    "disableApiTermination": {         
        "value": true     
    },     
    "instanceId": "i-1234567890abcdef0" 
}

After all mining workloads were deployed, the actor created a Lambda function with a configuration that bypasses IAM authentication and creates a public Lambda endpoint. The threat actor then added a permission to the Lambda function that allows the principal to invoke the function. The following examples show CreateFunctionUrlConfig and AddPermission request parameters.

CreateFunctionUrlConfig:

{     
    "authType": "NONE",     
    "functionName": "generate-service-a1b2c3d4" 
}

AddPermission:

{     
    "functionName": "generate-service-a1b2c3d4",     
    "functionUrlAuthType": "NONE",    
    "principal": "*",     
    "statementId": "FunctionURLAllowPublicAccess",     
    "action": "lambda:InvokeFunctionUrl" 
}

The threat actor concluded the persistence stage by creating an IAM user user-x1x2x3x4 and attaching the IAM policy AmazonSESFullAccess (CreateUser, AttachUserPolicy). They also created an access key and login profile for that user (CreateAccessKey, CreateLoginProfile). Based on the SES role that was attached to the user, it appears the threat actor was attempting Amazon Simple Email Service (Amazon SES) phishing.

To prevent public Lambda URLs from being created, organizations can deploy service control policies (SCPs) that deny creation or updating of Lambda URLs with an AuthType of “NONE”.

{   
    "Version": "2012-10-17",   
    "Statement": [     
        {       
            "Effect": "Deny",       
            "Action": [         
                "lambda:CreateFunctionUrlConfig",         
                "lambda:UpdateFunctionUrlConfig"       
            ],       
            "Resource": "arn:aws:lambda:*:*:function/*",       
            "Condition": {         
                "StringEquals": {           
                    "lambda:FunctionUrlAuthType": "NONE"         
                }       
            }     
        }   
    ] 
}

Detection methods using GuardDuty

The multilayered detection approach of GuardDuty proved highly effective in identifying all stages of the attack chain using threat intelligence, anomaly detection, and the recently launched Extended Threat Detection capabilities for EC2 and ECS.

Next, we walk through the details of these features and how you can deploy them to detect attacks such as these. You can enable GuardDuty foundational protection plan to receive alerts on crypto mining campaigns like the one described in this post. To further enhance detection capabilities, we highly recommend enabling GuardDuty Runtime Monitoring, which will extend finding coverage to system-level events on Amazon EC2, Amazon ECS, and Amazon Elastic Kubernetes Service (Amazon EKS).

GuardDuty EC2 findings

Threat intelligence findings for Amazon EC2 are part of the GuardDuty foundational protection plan, which will alert you to suspicious network behaviors involving your instances. These behaviors can include brute force attempts, connections to malicious or crypto domains, and other suspicious behaviors. Using third-party threat intelligence and internal threat intelligence, including active threat defense and MadPot, GuardDuty provides detection over the indicators in this post through the following findings: CryptoCurrency:EC2/BitcoinTool.B and CryptoCurrency:EC2/BitcoinTool.B!DNS.

GuardDuty IAM findings

The IAMUser/AnomalousBehavior findings spanning multiple tactic categories (PrivilegeEscalation, Impact, Discovery) showcase the ML capability of GuardDuty to detect deviations from normal user behavior. In the incident described in this post, the compromised credentials were detected due to the threat actor using them from an anomalous network and location and calling APIs that were unusual for the accounts.

GuardDuty Runtime Monitoring

GuardDuty Runtime Monitoring is an important component for Extended Threat Detection attack sequence correlation. Runtime Monitoring provides host level signals, such as operating system visibility, and extends detection coverage by analyzing system-level logs indicating malicious process execution at the host and container level, including the execution of crypto mining programs on your workloads. The CryptoCurrency:Runtime/BitcoinTool.B!DNS and CryptoCurrency:Runtime/BitcoinTool.B findings detect network connections to crypto-related domains and IPs, while the Impact:Runtime/CryptoMinerExecuted finding detects when a process running is associated with a cryptocurrency mining activity.

GuardDuty Extended Threat Detection

Launched at re:Invent 2025, AttackSequence:EC2/CompromisedInstanceGroup finding represents one of the latest Extended Threat Detection capabilities in GuardDuty. This feature uses AI and ML algorithms to automatically correlate security signals across multiple data sources to detect sophisticated attack patterns of EC2 resource groups. Although AttackSequences for EC2 are included in the GuardDuty foundational protection plan, we strongly recommend enabling Runtime Monitoring. Runtime Monitoring provides key insights and signals from compute environments, enabling detection of suspicious host-level activities and improving correlation of attack sequences. For AttackSequence:ECS/CompromisedCluster attack sequences, Runtime Monitoring is required to correlate container-level activity.

Monitoring and remediation recommendations

To protect against similar crypto mining attacks, AWS customers should prioritize strong identity and access management controls. Implement temporary credentials instead of long-term access keys, enforce multi-factor authentication (MFA) for all users, and apply least privilege to IAM principals limiting access to only required permissions. You can use AWS CloudTrail to log events across AWS services and combine logs into a single account to make them available to your security teams to access and monitor. To learn more, refer to Receiving CloudTrail log files from multiple accounts in the CloudTrail documentation.

Confirm GuardDuty is enabled across all accounts and Regions with Runtime Monitoring enabled for comprehensive coverage. Integrate GuardDuty with AWS Security Hub and Amazon EventBridge or third-party tooling to enable automated response workflows and rapid remediation of high-severity findings. Implement container security controls, including image scanning policies and monitoring for unusual CPU allocation requests in ECS task definitions. Finally, establish specific incident response procedures for crypto mining attacks, including documented steps to handle instances with disabled API termination—a technique used by this attacker to complicate remediation efforts.

If you believe your AWS account has been impacted by a crypto mining campaign, refer to remediation steps in the GuardDuty documentation: Remediating potentially compromised AWS credentials, Remediating a potentially compromised EC2 instance, and Remediating a potentially compromised ECS cluster.

To stay up to date on the latest techniques, visit the Threat Technique Catalog for AWS.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Kyle Koeller
Kyle Koeller

Kyle is a security engineer in the GuardDuty team with a focus on threat detection. He is passionate about cloud threat detection and offensive security, and he holds the following certifications: CompTIA Security+, PenTest+, CompTIA Network Vulnerability Assessment Professional, and SecurityX. When not working, Kyle enjoys spending his time in the gym and exploring New York City.

Building zero trust generative AI applications in healthcare with AWS Nitro Enclaves

Post Syndicated from Nathan Pogue original https://aws.amazon.com/blogs/compute/building-zero-trust-generative-ai-applications-in-healthcare-with-aws-nitro-enclaves/

In healthcare, generative AI is transforming how medical professionals analyze data, summarize clinical notes, and generate insights to improve patient outcomes. From automating medical documentation to assisting in diagnostic reasoning, large language models (LLMs) have the potential to augment clinical workflows and accelerate research. However, these innovations also introduce significant privacy, security, and intellectual property challenges.

Healthcare data often contains Protected Health Information (PHI), which is governed by strict regulations and compliance frameworks. At the same time, organizations or researchers who have invested substantial time and compute resources into training medical LLMs must protect their proprietary model architectures, weights, and fine-tuned datasets. Traditional deployment models necessitate mutual trust between the model publisher and the healthcare data provider — trust that sensitive data won’t be leaked, and that the model itself won’t be copied, tampered with, or exfiltrated. The absence of a secure and verifiable trust model between model publishers and consumers remains one of the main barriers to scaling generative AI in regulated medical environments.

To address this concern, both parties need a secure environment to publish and consume models without exposing data or intellectual property. Amazon Web Services (AWS) Nitro Enclaves provide isolated, attested, and cryptographically verified compute environments that help protect sensitive workloads. Model owners can encrypt their LLMs with AWS Key Management Service (AWS KMS) and allow only verified Nitro Enclaves to decrypt and run them, making sure that the model can’t be accessed outside the Nitro Enclave. Healthcare organizations and consumers can use this to process sensitive data within their own AWS environment entirely within the Nitro Enclave, helping keep PHI private and contained. Hardware-based attestation provides proof that the Nitro Enclave is running trusted code, so that both sides can exchange information with confidence.

In this post, we demonstrate how to deploy a publicly available foundational model (FM) using Nitro Enclaves for isolated, more secure compute, AWS KMS for model encryption, Amazon Simple Storage Service (Amazon S3) for storing model artifacts and images, and Amazon Simple Queue Service (Amazon SQS) for securely delivering queries, enabling private, privacy-preserving inferences while helping protect both model intellectual property and sensitive patient data.

Solution overview

This solution outlines how to build a more secure end-to-end pipeline that enables zero trust medical LLM publication and inference with Nitro Enclaves. This post demonstrates a guide for setting up an Amazon Elastic Compute Cloud (Amazon EC2) instance with Nitro Enclaves enabled, downloading and encrypting a publicly available FM to an S3 bucket with an AWS KMS key, sending medical text and image-based queries to an SQS queue for processing, and storing results in an Amazon DynamoDB table.

This project is intended solely for educational and demonstration purposes and isn’t suitable for production or clinical use. Its outputs aren’t validated for clinical accuracy and must not be used for patient care or medical decision-making. Before any real-world deployment, make sure that you implement comprehensive security, privacy, and compliance safeguards. These include health data protection controls, secrets management, and regulatory validation. Furthermore, you must consult the appropriate clinical, legal, and security experts.

For demonstration purposes, this solution is deployed in a single AWS account. Ideally, in production, it would be deployed across separate AWS accounts: one for the model owner and one for the model consumer. The model owner can use cross-account AWS Identity and Access Management (IAM) permissions and encrypted model sharing through AWS KMS to securely provide access to their model without exposing the underlying weights or logic. At the same time, the consumer can run sensitive inferences within their own environment, maintaining strict data privacy and zero trust principles. In a real-world implementation, the model provider should also establish a robust entitlement and licensing framework to manage customer access, enabling fine-grained control over who can invoke the model, track usage, and support license revocation to immediately remove permissions from specific customers when necessary.

The following diagram shows the solution architecture:

Scope of solution

The steps of the solution include:

  1. Amazon EC2 setup: An EC2 instance is launched with Nitro Enclaves and Trusted Platform Module (TPM) enabled. For this project, a c7i.12xlarge instance with a 150 GB Amazon EBS volume is used to provide the necessary compute resources for running LLMs.
  2. Public FM download: A publicly available FM is retrieved from Hugging Face and stored in an S3 bucket within the model consumer’s AWS account.
  3. Model encryption: The model is encrypted using AWS KMS envelope encryption. Only a Nitro Enclave presenting a valid attestation document can request the decryption key from AWS KMS, which helps prevent unauthorized access to the model weights outside the Nitro Enclave.
  4. Nitro Enclave setup: A Docker image containing the llama.cpp inference runtime is built and deployed inside the Nitro Enclave.
  5. Model decryption and setup: When the Nitro Enclave launched, it requests decryption of the model artifacts using its attestation credentials. Then, the model can be securely decrypted inside the memory of the Nitro Enclave and loaded by the llama.cpp server. This means that the decrypted model weights aren’t visible outside of the Nitro Enclave boundary.
  6. Medical query: Users can submit either text or image-based queries to the model. Queries are sent through vsock, a secure communication channel from the client application to the model server inside the Nitro Enclave. Image queries necessitate that users upload images to an S3 bucket. The upload event triggers an SQS queue, which signals the Amazon EC2 parent to fetch and send the image to the Nitro Enclave image for the medical LLM to process with its multimodal capabilities.
  7. Message history: Each interaction, including the user’s prompt and the model’s response, is logged to a DynamoDB table. This provides a persistent conversation history that enables traceability and auditing while keeping PHI securely stored within the consumer’s account. If necessary, the DynamoDB table can be encrypted and sealed for another layer of security and privacy.

About Google MedGemma 4B

Google MedGemma is a family of medically-optimized LLMs built on Gemma 3, with 4B and 27B parameter variants supporting both text and multimodal versions for medical image inputs. The 4B model offers efficiency and strong performance for multimodal tasks such as report generation and medical Q&A, while the 27B models excel at more demanding scenarios, such as electronic health record interpretation and complex longitudinal data analysis.

MedGemma models are well-suited for automated radiology report generation, clinical triage and documentation, patient education, medical image pre-interpretation, and medical education systems. The 4B model is ideal for portable or resource-constrained deployments, whereas the 27B multimodal delivers maximal performance.

In this project, MedGemma 4B serves as a reference medical LLM, showing how domain-adapted fine-tuning can enhance a model’s ability to interpret, reason about, and respond to complex medical queries. It also provides a foundation for exploring the safe and effective use of LLMs in healthcare applications, while being securely deployed within a Nitro Enclave. However, you can choose to deploy your own medical FM if needed. This is a deeper overview on the 4B model.

Prerequisites

To implement the proposed solution, make sure that you have the following:

  • The AWS Command Line Interface (AWS CLI) installed on your machine to create the EC2 instance.
  • AWS permissions with access to EC2 c7i.12xlarge instances and Nitro Enclaves.
  • Knowledge of Amazon S3, AWS KMS, Amazon SQS, AWS Lambda, and DynamoDB.
  • Basic knowledge of Nitro Enclaves and healthcare data security.
  • The GitHub repository cloned to your local machine.

Environment setup

The following sections outline how to set up your environment for this solution.

Create S3 buckets

In this solution, you create two S3 buckets: one for the model artifacts and one for the image inputs.

To create the S3 buckets

  1. Sign in to the Amazon S3 console, choose Create bucket, and follow the prompts to create a new S3 bucket.
  2. For the model artifact bucket, give it a unique name (for example AWSACCOUNTNUMBER-medgemma-model) in the same Region you use for the other project resources.
  3. Repeat the same process for the image bucket (for example AWSACCOUNTNUMBER-medgemma-image-inputs).
  4. Update the S3_BUCKET_NAME variable with your model bucket name in envelope_encrypt_model.sh and run.sh.

Create an SQS queue

When images are uploaded to the S3 image bucket, they are sent to an SQS queue for processing in sequential order by the model running in the Nitro Enclave.

To create an SQS queue

  1. Sign in to the Amazon SQS console, choose Create queue, and follow the prompts to create a new SQS queue.
  2. Choose Standard Queue, provide a name, leave the rest as default, and choose Create queue.
  3. Replace the SQS_QUEUE_URL variable in image_processor.py and lambda_function.py (in the client and assets folder, respectively) with your URL.

Create a Lambda function

For image-based queries, MedGemma 4B expects images encoded in base64 format to be passed in the prompt. To convert the images to this format, a Lambda function is invoked using an Amazon S3 trigger when an image is uploaded to the bucket.

To create a Lambda function

  1. Sign in to the Lambda console, choose Create function, and follow the prompts to create a new Lambda function from scratch.
  2. Choose a name, choose a Python runtime (for example Python 3.13), and paste in the Lambda function code from the assets folder.
  3. Next, update the Lambda function’s IAM role in Permissions under the Configuration tab with access to your S3 image bucket and the SQS queue that you created with inline policy permissions. Attach the following policies:
    1. Amazon S3 policy:
      {
       "Version": "2012-10-17",
       "Statement": [
           {
               "Sid": "Statement1",
               "Effect": "Allow",
               "Action": [
                   "s3:*"
               ],
               "Resource": [
                   "arn:aws:s3:::<IMAGE_BUCKET_NAME>",
                   "arn:aws:s3:::<IMAGE_BUCKET_NAME>/*"
               ]
           }
       ]
      }

    2. Amazon SQS policy:
      {
       "Version": "2012-10-17",
       "Statement": [
           {
               "Sid": "VisualEditor0",
               "Effect": "Allow",
               "Action": "sqs:ListQueues",
               "Resource": "*"
           },
           {
               "Sid": "VisualEditor1",
               "Effect": "Allow",
               "Action": "sqs:*",
              "Resource": "arn:aws:sqs:<REGION>:<ACCOUNT_NUMBER>:<QUEUE_NAME>"
           }
       ]
      }

  4. Finally, within the Lambda Designer, add a trigger, choose Amazon S3, and choose your image bucket. You should see the following example when the trigger is enabled.

AWS Lambda configuration interface showing S3 bucket trigger setup for medical image processing workflow

Create a DynamoDB table

When the queries have been processed by the model for inference, the prompts and responses are logged to a DynamoDB table for auditing and message history purposes.

To create a DynamoDB table

  1. Sign in to the DynamoDB console, choose Create table, and follow the prompts to create a new DynamoDB table.
  2. Give it a partition key named ID as a String type.
  3. Replace the TABLE_NAME variable with the table name and REGION variable with your AWS Region in direct_query.py and image_processor.py files.

Create an AWS KMS key

An AWS KMS key is used to envelope-encrypt the model artifacts before they are uploaded to the S3 model bucket. During encryption, the AWS KMS key policy is configured with conditions that restrict decryption to only those Nitro Enclaves presenting a valid attestation document. This attestation includes platform configuration registers (PCR) hashes that represent the measured state of the Nitro Enclave, which covers the signed Nitro Enclave image, runtime, and configuration. When the Nitro Enclave is launched, it generates an attestation document signed by the Amazon EC2 Nitro hypervisor, proving that its PCR values match the expected trusted measurements defined in the AWS KMS key policy. The key is released only if these PCR hashes align and the attestation is verified by AWS KMS, allowing the Nitro Enclave to decrypt and load the model securely in memory.

To create an AWS KMS key

  1. Sign in to the AWS KMS console, choose Create key, and follow the prompts to create a new AWS KMS key.
  2. Choose Symmetric as the key type and Encrypt and decrypt for the key usage. Make the alias AppKmsKey. Leave the default settings and choose Finish.
  3. Replace the REGION variable in vsock-proxy.yaml in the client folder with your AWS Region.

Create an EC2 instance

Now that the necessary resources are set up, you can proceed to launch the EC2 instance and create the Nitro Enclave image. For this solution, a c7i.12xlarge instance with a 150 GB EBS volume is provisioned.

To launch an EC2 instance with Nitro Enclaves enabled

  1. Within the GitHub repository on your local machine, run ./create_ec2.sh to create the EC2 instance.
cd scripts 
chmod +x create_ec2.sh 
./create_ec2.sh

  1. The script launches an EC2 instance called MedGemmaNitroEnclaveDemo. When the instance is running, you must create an IAM policy and add it to the Amazon EC2 IAM role with necessary permissions to the resources created previously.
  2. Sign in to the IAM console and navigate to Policies, choose Create policy, choose JSON, and paste the following policy, making sure that you update the bucket, queue URL, AWS Region, account number, and table variables:
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "s3modelbucket",
      "Effect": "Allow",
      "Action": [
        "s3:*"
      ],
      "Resource": [
        "arn:aws:s3:::<MODEL_BUCKET_NAME>",
        "arn:aws:s3:::<MODEL_BUCKET_NAME>/*"
      ]
    },
    {
      "Sid": "dynamodb",
      "Effect": "Allow",
      "Action": [
        "dynamodb:*"
      ],
      "Resource": [
        "arn:aws:dynamodb:<REGION>:<ACCOUNT_NUMBER>:table/<TABLE_NAME>"
      ]
    },
    {
      "Sid": "sqslist",
      "Effect": "Allow",
      "Action": "sqs:ListQueues",
      "Resource": "*"
    },
    {
      "Sid": "sqsqueue",
      "Effect": "Allow",
      "Action": "sqs:*",
      "Resource": "arn:aws:sqs:<REGION>:<ACCOUNT_NUMBER>:<QUEUE_NAME>"
    }
  ]
}
  1. Give it a name (for example enclave-permissions) and choose Create policy.
  2. Navigate to Roles, choose Create role, choose EC2 as the AWS service for the Trusted entity type, then choose your policy that you created under Add permissions.
  3. Update your EC2 instance to use the role by going to the Security setting under the Actions dropdown, then modifying its IAM role.
  4. You can upload the modified repository to your EC2 instance using SCP. Alternatively, you can transfer the repository through rsync
rsync -avz -e "ssh -i /path/to/directory/sample-for-secure-medical-llm-inference-with-nitro-enclaves/nitro-enclave-key.pem" --exclude='*.pem' /path/to/directory/sample-for-secure-medical-llm-inference-with-nitro-enclaves/ ec2-user@<PUBLIC_IP>:~ 
cd sample-for-secure-medical-llm-inference-with-nitro-enclaves
  1. Make the scripts executable (in client, server and scripts).
chmod +x *.sh

Nitro Enclave setup

With Amazon EC2 loaded with the necessary scripts, you can begin building the Nitro Enclave image. During this process, the Docker container is converted into an Enclave Image File (EIF), which generates cryptographic measurements (PCR hashes) that uniquely identify the code and configuration of the enclave. These measurements are embedded into the AWS KMS key policy, creating a hardware-attested trust boundary that makes sure only this specific, unmodified Nitro Enclave can decrypt and access the model weights.

  1. Run the complete setup script, which sets up the client on the EC2 parent instance and the server running within the Nitro Enclave. You can observe the different scripts in the client, server, and scripts folders.
sudo ./run_complete_setup.sh
  1. The various scripts run to download the MedGemma 4B model, encrypt the model with the AWS KMS key, build a Docker image to run a llama.cpp server, start a Nitro Enclave, and decrypt and run the model. This process takes approximately 10 minutes.
  2. When the Nitro Enclave is running, it runs in debug mode so that you can observe the various startup logs outputted. Wait until llama.cpp server logs are outputted that indicate the server is ready and listening.

Inference examples

When the model is decrypted and running on the llama.cpp server within the Nitro Enclave, you can begin to invoke the model with either image or text-based queries. Open a new terminal session in your EC2 instance. You can navigate to the client folder to run the scripts for queries.

Image-based queries

For inference on medical images, upload an image to your Amazon S3 image bucket. When it is uploaded, run python3 image_processor.py to pass the image from the SQS queue to the Nitro Enclave for processing. The following are examples of image inputs and model outputs.

Brain CT scan:

Medical brain CT scan image showing anatomical structures in grayscale

Case courtesy of Dr Henry Knipe, Radiopaedia.org, rID: 46289

Model response:Complete processing log showing secure medical image analysis pipeline from upload through diagnostic outputChest X-ray:

Chest X-ray image in AP sitting position

Model response:Model inference logs showing automated chest X-ray analysis with detailed radiological findings and considerationsText-based queries

For inference on text-queries, run python3 direct_query.py "<YOUR_MEDICAL_QUERY>" to invoke the model. The following are examples of text-based inputs and model outputs.

Basic usage:

python3 direct_query.py "What are the symptoms of pneumonia?"

Model response:Model inference output describing pneumonia symptoms, diagnosis, and treatment optionsLab result interpretation:

python3 direct_query.py "Patient has elevated troponin levels (15.2 ng/mL), elevated CK-MB, and ST elevation in leads II, III, aVF. What does this suggest?"

Model response:Model inference output analyzing cardiac lab results and ECG findings

Cleaning up

To avoid incurring future charges, delete the resources used in this solution:

  1. Stop and terminate the EC2 instance.
  2. Empty and delete the S3 buckets.
  3. Delete the DynamoDB table.
  4. Delete the SQS queue.
  5. Delete the AWS KMS Key.
  6. Delete the Lambda function.

Conclusion

You can combine the isolation and attestation capabilities of AWS Nitro Enclaves, the encryption controls of AWS KMS, and the scalability of services such as Amazon S3, Amazon SQS, and Amazon DynamoDB to build a more secure, zero trust pipeline for deploying generative AI models in healthcare. Using Google MedGemma 4B as your reference medical LLM, you can enable privacy-preserving inference where both PHI and model intellectual property remain protected. For more information, consult the following resources:

Introducing Amazon EC2 X8aedz instances powered by 5th Gen AMD EPYC processors for memory-intensive workloads

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-amazon-ec2-x8aedz-instances-powered-by-5th-gen-amd-epyc-processors-for-memory-intensive-workloads/

Today, we’re announcing the availability of new memory-optimized, high-frequency Amazon Elastic Compute Cloud (Amazon EC2) X8aedz instances powered by a 5th Gen AMD EPYC processor. These instances offer the highest CPU frequency, 5GHz in the cloud. They deliver up to two times higher compute performance and 31% price-performance compared to previous generation X2iezn instances.

X8aedz instances are ideal for electronic design automation (EDA) workloads, such as physical layout and physical verification jobs, and relational databases that benefit from high single-threaded processor performance and a large memory footprint. The combination of 5 GHz processors and local NVMe storage enables faster processing of memory-intensive backend EDA workloads such as floor planning, logic placement, clock tree synthesis (CTS), routing, and power/signal integrity analysis. The high memory-to-vCPU ratio of 32:1 makes these instances particularly effective for applications with vCPU-based licensing models.

Let me explain the instance type naming: The “a” suffix indicates an AMD processor, “e” denotes extended memory in the memory-optimized instance family, “d” represents local NVMe-based SSDs physically connected to the host server, and “z” indicates high-frequency processors.

X8aedz instances
X8aedz instances are available in eight sizes ranging from 2–96 vCPUs with 64–3,072 GiB of memory, including two bare metal sizes. X8aedz instances feature up to 75 Gbps of network bandwidth with support for the Elastic Fabric Adapter (EFA), up to 60 Gbps of throughput to the Amazon Elastic Block Store (Amazon EBS), and up to 8 TB of local NVMe SSD storage.

Here are the specs for X8aedz instances:

Instance name vCPUs Memory
(GiB)
NVMe SSD storage (GB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
x8aedz.large 2 64 158 Up to 18.75 Up to 15
x8aedz.xlarge 4 128 316 Up to 18.75 Up to 15
x8aedz.3xlarge 12 384 950 Up to 18.75 Up to 15
x8aedz.6xlarge 24 768 1,900 18.75 15
x8aedz.12xlarge 48 1,536 3,800 37.5 30
x8aedz.24xlarge 96 3,072 7,600 75 60
x8aedz.metal-12xl 48 1,536 3,800 37.5 30
x8aedz.metal-24xl 96 3,072 7,600 75 60

With the 60 Gbps Amazon EBS bandwidth and up to 8 TB of local NVMe SSD storage, you can achieve faster database response times and reduced latency for EDA operations, ultimately accelerating time-to-market for chip designs. These instances also support the instance bandwidth configuration feature that offers flexibility in allocating resources between network and EBS bandwidth. You can scale network or EBS bandwidth by 25% and improve database (read and write) performance, query processing, and logging speeds.

X8aedz instances use sixth-generation AWS Nitro cards, which offload CPU virtualization, storage, and networking functions to dedicated hardware and software, enhancing performance and security for your workloads.

Now available
Amazon EC2 X8aedz instances are now available in US West (Oregon) and Asia Pacific (Tokyo) AWS Regions, and additional Regions will be coming soon. For Regional availability and future roadmap, search the instance type in the AWS CloudFormation resources tab of the AWS Capabilities by Region.

You can purchase these instances as On-Demand, Savings Plan, Spot Instances, and Dedicated Instances. To learn more, visit the Amazon EC2 Pricing page.

Give X8aedz instances a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 X8aedz instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

Amazon GuardDuty adds Extended Threat Detection for Amazon EC2 and Amazon ECS

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/amazon-guardduty-adds-extended-threat-detection-for-amazon-ec2-and-amazon-ecs/

Today, we’re announcing new enhancements to Amazon GuardDuty Extended Threat Detection with the addition of two attack sequence findings for Amazon Elastic Compute Cloud (Amazon EC2) instances and Amazon Elastic Container Service (Amazon ECS) tasks. These new findings build on the existing Extended Threat Detection capabilities, which already combine sequences involving AWS Identity and Access Management (IAM) credential misuse, unusual Amazon Simple Storage service (Amazon S3) bucket activity, and Amazon Elastic Kubernetes Service (Amazon EKS) cluster compromise. By adding coverage for EC2 instance groups and ECS clusters, this launch expands sequence-level visibility to virtual machine and container environments that support the same application. Together, these capabilities provide a more consistent and unified way to detect multistage activity across diverse Amazon Web Services (AWS) workloads.

Modern cloud environments are dynamic and distributed, often running virtual machines, containers, and serverless workloads at scale. Security teams strive to maintain visibility across these environments and connect related activities that might indicate complex, multistage attack sequences. These sequences can involve multiple steps, such as establishing initial access and persistence, providing missing credentials or performing unexpected data access, that unfold over time and across different sources. GuardDuty Extended Threat Detection automatically links these signals using AI and machine learning (ML) models trained at AWS scale to build a complete picture of the activity and surface high-confidence insights to help customers prioritize response actions. By combining evidence from diverse sources, this analysis produces high-fidelity, unified findings that would otherwise be difficult to infer from individual events.

How it works
Extended Threat Detection analyzes multiple types of security signals, including runtime activity, malware detections, VPC Flow Logs, DNS queries, and AWS CloudTrail events to identify patterns that represent a multistage attack across Amazon EC2 and Amazon ECS workloads. Detection works with the GuardDuty foundational plan, and turning on Runtime Monitoring for EC2 or ECS adds deeper process and network-level telemetry that strengthens signal analysis and increases the completeness of each attack sequence.

The new attack sequence findings combine runtime and other observed behaviors across the environment into a single critical-severity sequence. Each sequence includes an incident summary, a timeline of observed events, mapped MITRE ATT&CK® tactics and techniques, and remediation guidance to help you understand how the activity unfolded and which resources were affected.

EC2 instances and ECS tasks are often created and replaced automatically through Auto Scaling groups, shared launch templates, Amazon Machine Images (AMIs), IAM instance profiles, or cluster-level deployments. Because these resources commonly operate as part of the same application, activity observed across them might originate from a single underlying compromise. The new EC2 and ECS findings analyze these shared attributes and consolidate related signals into one sequence when GuardDuty detects a pattern affecting the group.

When a sequence is detected, the GuardDuty console highlights any critical-severity sequence findings on the Summary page, with the affected EC2 instance group or ECS cluster already identified. Selecting a finding opens a consolidated view that shows how the resources are connected, which signals contributed to the sequence, and how the activity progressed over time, helping you quickly understand the scope of impact across virtual machine and container workloads.

In addition to viewing sequences in the console, you can also see these findings in AWS Security Hub, where they appear on the new exposure dashboards alongside other GuardDuty findings to help you understand your overall security risk in one place. This detailed view establishes the context for interpreting how the analysis brings related signals together into a broader attack sequence.

Together, the analysis model and grouping logic give you a clearer, consolidated view of activity across virtual machine and container workloads, helping you focus on the events that matter instead of investigating numerous individual findings. By unifying related behaviors into a single sequence, Extended Threat Detection helps you assess the full context of an attack path and prioritize the most urgent remediation actions.

Now available
Amazon GuardDuty Extended Threat Detection with expanded coverage for EC2 instances and ECS tasks is now available in all AWS Regions where GuardDuty is offered. You can start using this capability today to detect coordinated, multistage activity across virtual machine and container workloads by combining signals from runtime activity, malware execution, and AWS API activity.

This expansion complements the existing Extended Threat Detection capabilities for Amazon EKS, providing unified visibility into coordinated, multistage activity across your AWS compute environment. To learn more, visit the Amazon GuardDuty product page.

–Betty

Performance benefits of new Amazon EC2 R8a memory-optimized instances

Post Syndicated from Tyler Jones original https://aws.amazon.com/blogs/compute/performance-benefits-of-new-amazon-ec2-r8a-memory-optimized-instances/

Recently we announced the availability of Amazon Elastic Compute Cloud (Amazon EC2) R8a instances, the latest addition to the AMD memory-optimized instance family. These instances are powered by the 5th Generation AMD EPYC (codename Turin) processors with a maximum frequency of 4.5 GHz. In this post I take these instances for a spin and benchmark MySQL later on, but first I discuss the top things you should know about these instances.

Notable characteristics of R8a instances

Each vCPU on an R8a instance corresponds to a physical CPU core (something we started on 7th generation AMD instances). This means that there is no simultaneous multi-threading (SMT). Each vCPU mapped to a dedicated physical core, which means that you get more predictable and consistent performance because there’s no resource sharing or potential interference between threads, which is particularly crucial for performance-sensitive workloads where consistent latency is essential. When evaluating and adopting R8a instances, make sure that you’re re-evaluating your thresholds for CPU usage. You can likely squeeze more out of each instance’s CPU without impacting any of your workload’s SLA metrics.

R8a instances feature sizes of up to 192 vCPU with 1,536 GiB RAM. The following table shows the detailed specs:

Instance size vCPU Memory (GiB) Instance storage Network bandwidth (Gbps) EBS bandwidth (Gbps)
r8a.medium 1 8 EBS Only Up to 12.5 Up to 10
r8a.large 2 16 EBS Only Up to 12.5 Up to 10
r8a.xlarge 4 32 EBS Only Up to 12.5 Up to 10
r8a.2xlarge 8 64 EBS Only Up to 15 Up to 10
r8a.4xlarge 16 128 EBS Only Up to 15 Up to 10
r8a.8xlarge 32 256 EBS Only 15 10
r8a.12xlarge 48 384 EBS Only 22.5 15
r8a.16xlarge 64 512 EBS Only 30 20
r8a.24xlarge 96 768 EBS Only 40 30
r8a.48xlarge 192 1536 EBS Only 75 60
r8a.metal-24xl 96 768 EBS Only 40 30
r8a.metal-48xl 192 1536 EBS Only 75 60

Testing MySQL performance using HammerDB

R8a instances are a great choice for MySQL databases, so I thought that would be a great place to showcase some of these instances capabilities. To test MySQL, I used a series of scripts written by my colleagues to track MySQL performance across software versions and different EC2 instances. These scripts are stored in the repro-collection repository, which is an open source, extensible framework for performance testing that addresses real-world workloads rather than micro-benchmarks. It is built to provide a performance measurement reference usable across multiple organizations, and it’s currently centered on MySQL and actively used in discussions with Linux Kernel developers and maintainers. Furthermore, it helps track any performance impacts created by code changes to MySQL. The scripts contained in this repository set up a MySQL database to be tested, and a load generator running the HammerDB benchmark.

For this benchmark I used an r6a.24xlarge instance for the load generator, and an r6a.xlarge, r7a.xlarge, and r8a.xlarge instances for the MySQL database server all deployed in the same AWS Availability Zone (AZ). I chose a single AZ setup to minimize any latency variability from crossing multiple AZs. This is not meant to be a production-like setup, and I highly recommend using multiple AZs for production workloads. Each MySQL instance was tested separately using the same HammerDB load generator. Each test was run three times, and the results were averaged across the three runs. A diagram of the architecture is shown in the following figure:

Performance testing architecture showing r6a/r7a/r8a instance types with HammerDB load generator executing 9 test runs

HammerDB overall results

R8a instances show great results in the HammerDB benchmark for MySQL databases. For HammerDB’s overall score category, R8a instances outscored R7a instances by 55% and outscored R6a instances by 74%.

Performance comparison chart showing r6a, r7a, and r8a instance scores

HammerDB transactions per minute test

R8a instances also showed a notable improvement in this category. When compared to previous generation R7a instances, R8a out performed R7a by 32%. When compared to R6a instances, R8a outperformed by 63%.

 Performance comparison showing r6a (91,105), r7a (112,686), and r8a (148,478) transactions per minute

HammerDB P99 latency results

R8a instances showed improvement in P99 latency results, showing the efficiency gains driven by the new 5th Generation AMD EPYC CPUs and higher memory bandwidth. R8a shows an 14% latency reduction when compared to R7a, and a 25% latency reduction when compared to R6a.

P99 latency comparison showing decrease from 39.93ms (r6a) to 30.02ms (r8a) across instance generations

Conclusion

Built on the AWS Nitro System using sixth generation Nitro Cards, R8a instances are ideal for high performance, memory-intensive workloads, such as SQL and NoSQL databases, as demonstrated by the bench-marking shown in this post, as well as distributed web scale in-memory caches, in-memory databases, real-time big data analytics, and Electronic Design Automation (EDA) applications. R8a instances offer 12 sizes, including 2 bare metal sizes. Amazon EC2 R8a instances are SAP-certified, and providing 38% more SAPS when compared to R7a instances. If you’re still running 6th generation R6a instances, then I highly encourage you to migrate to the 8th generation instances to use their clear price performance benefits. Staying on modern infrastructure is a great way to drive down costs and provide more features for your customers, and there are clear gains to be had based on the testing shown in this post.

Start optimizing your high performance memory intensive workloads today by migrating to R8a instances. Visit the Amazon EC2 R8a instances page to learn more and get started on your upgrades to use the increased price performance of R8a instances today!

Optimize unused capacity with Amazon EC2 interruptible capacity reservations

Post Syndicated from Shubham Sarin original https://aws.amazon.com/blogs/compute/optimize-unused-capacity-with-amazon-ec2-interruptible-capacity-reservations/

Organizations running critical workloads on Amazon Elastic Compute Cloud (Amazon EC2) reserve compute capacity using On-Demand Capacity Reservations (ODCR) to have availability when needed. However, reserved capacity can intermittently sit idle during off-peak periods, between deployments, or when workloads scale down. This unused capacity represents a missed opportunity for cost optimization and resource efficiency across the organization.

Amazon EC2 now offers interruptible ODCRs, a new capability that lets you make unused compute capacity temporarily available to other workloads while maintaining control to reclaim it. This feature helps you optimize reservations and reduce costs across your AWS organization.

In this post, we explore how this works through a practical customer scenario.

Customer scenario: Maximizing reservation utilization across

Consider a financial services company where the trading platform team maintains a large fleet of r7i.4xlarge instances reserved around-the-clock for critical blue/green deployments. During off-peak trading hours and weekends, a significant portion of this reserved capacity sits idle. Meanwhile, the data analytics team regularly runs batch processing jobs for risk modeling—workloads that could benefit from additional compute capacity but don’t require the same availability guarantees as the trading platform.

Previously, sharing this capacity meant losing control over when it could be reclaimed, creating operational challenges when the trading platform needed to scale up quickly during market volatility. Interruptible ODCRs solve this problem by giving the reservation owner control to reclaim capacity when needed for critical operations.

In the following sections, we walk through the key steps to configure capacity sharing, launch instances, and reclaim capacity. The high-level steps are:

  1. Set up capacity sharing
  2. Discover available capacity and launch instances
  3. Reclaim capacity and handle interruptions

Step 1: Set up capacity sharing

The trading platform team begins by identifying unused capacity patterns through Amazon EC2 Capacity Manager. They determine that approximately 60% of their reserved r7i.4xlarge capacity remains unused during overnight hours and weekends.

Create interruptible ODCR

For prerequisites, see Interruptible Capacity Reservations for capacity owners in the Amazon EC2 User Guide.

To repurpose this idle capacity, the trading platform team creates an interruptible ODCR using the AWS Management Console, SDK, or AWS Command Line Interface (AWS CLI). To use the console, they complete the following steps:

  1. On the Amazon EC2 console, choose Capacity Reservations in the navigation pane.
  2. Select the source ODCR and choose Create interruptible reservation.
  3. For Instances to allocate, enter how many instances to allocate (out of a 100-instance reservation). For this example, we allocate 60 instances.
  4. Choose Create interruptible reservation.

This configuration withdraws 60 instances from their original reservation and creates a new ODCR with interruptible configuration. The original reservation now shows 40 instances, and the new interruptible reservation shows 60.

Create interruptible on-demand capacity reservation

Share resources across the organization

With the interruptible reservation created, the reservation owning team uses AWS Resource Access Manager (AWS RAM)—a service that helps you securely share AWS resources across accounts and organizations—to share the newly created ODCR with additional accounts in their organization. When sharing your ODCR, you specify which consumer account IDs in your organization will get access to the interruptible ODCR. Alternatively, you can share the ODCR with your entire AWS Organization or Organizational Unit (OU). When it’s complete, the specified accounts get access to the interruptible ODCR capacity and establish a setup like the one illustrated in the following diagram.

Share resources across the organization

Sharing with all accounts (at once) within the organization requires organization-wide sharing to be enabled in AWS Organizations setup. If organization-wide sharing is not enabled, a user can still share with individual accounts by enumerating each account.

Step 2: Discover available capacity and launch instances

After the reservation owner (the trading platform team) shares their reservation, the capacity consumer (data analytics team) needs to find the capacity in their account and launch into it. In this section, we walk through the interruptible ODCR discovery and launch process.

Discover available capacity

The data analytics team, running batch processing jobs in a separate AWS account, can now find the shared interruptible capacity in their account using the console, SDK, or AWS CLI. To use the console, they complete the following steps:

  1. On the Amazon EC2 console, choose Capacity Reservations in the navigation pane.
  2. Choose the ODCR to view its details page.

The interruptible reservation appears with a clear indication that it’s interruptible, showing the instance type (r7i.4xlarge), Availability Zone, and available capacity.

Discover available capacity

Configure Auto Scaling groups for interruptible capacity

To use this capacity for their batch processing workloads, the analytics team creates a new launch template specifically designed for interruptible capacity. The key configuration element is setting the new market-type parameter and targeting the interruptible ODCR.

In the launch template, specify the following:

  • Instance type: r7i.4xlarge (matching the shared capacity)
  • Capacity reservation specification: Targeted
  • Capacity reservation ID: Enter the ID of the shared interruptible ODCR
  • Market type: Use the type interruptible-capacity-reservation

Next, create an Auto Scaling group that uses this launch template. The group is configured as follows:

  • Minimum size: 0 (to avoid unnecessary costs when capacity isn’t needed)
  • Maximum size: 40 (within the available shared capacity)
  • Desired capacity: Set based on job queue length

Launch instances into interruptible capacity

When the analytics team’s batch processing jobs trigger scaling events, the Auto Scaling group launches instances that automatically target the shared interruptible ODCR. These instances launch immediately if capacity is available, providing the team with access to reserved capacity for their fault-tolerant workloads. The instances appear on the Amazon EC2 console with their instance lifecycle as interruptible-capacity-reservation and the ODCR ID in which they’re running. This provides clear indication that they’re running on interruptible capacity, helping with monitoring and cost allocation.

Step 3: Reclaim capacity and handle interruptions

In this section, we review how the capacity owner (the trading platform team) can reclaim their capacity when needed for their critical operations and how the capacity consumer can gracefully handle such interruptions.

Trigger reclamation

When market volatility increases and the trading platform needs to scale up quickly, the platform team initiates capacity reclamation through the console, SDK, or AWS CLI. To use the console, they complete the following steps:

  1. On the Amazon EC2 console, choose Capacity Reservations in the navigation pane.
  2. Choose the ODCR to view its details page.
  3. Choose Edit Interruptible Allocation.
  4. Specify how many instances are needed back (in this case, all 60 instances for maximum trading capacity).
  5. Choose Update, then choose Confirm.

Edit interruptible allocation

The reclamation process can also be automated using AWS Lambda functions triggered by Amazon CloudWatch alarms or scheduled events, providing proactive capacity management based on predictable usage patterns.

Consumer notification and graceful shutdown

After the owner triggers capacity reclamation, consuming instances receive a 2-minute instance interruption warning notice through Amazon EventBridge. The analytics team has configured their batch processing applications to listen for these events. Their applications receive this 2-minute warning and immediately begin checkpointing their current work, saving intermediate results to Amazon Simple Storage Service (Amazon S3), and gracefully shutting down. For EventBridge notification details, refer to the Monitor interruptible Capacity Reservations with EventBridge section in the EC2 Capacity Reservations User Guide.

Automatic capacity restoration to source ODCR

After the 2-minute notice period, Amazon EC2 starts shutting down the consuming instances. After the instances are successfully shut down, Amazon EC2 restores the capacity to the trading platform’s original ODCR. The trading platform can then launch their critical workloads into the same ODCR, resulting in minimal delay for their scaling requirements. The reservation owner can track their capacity reclamation status through the console or API. On the Amazon EC2 console, the ODCR details page shows the current instance allocation, target instance allocation, and request status. When current and target counts match, the status changes to Active, confirming completion.

After the reservation owner requests their capacity back, the capacity reclamation process can take a few minutes, so reservation owners should account for this delay when planning critical activities. This is because Amazon EC2 provides a 2-minute warning to the consumer instances, followed by the instance shutdown period.

Billing and cost considerations

The billing model for interruptible ODCRs follows a clear usage-based approach that aligns costs with consumption:

  • Reservation owner (trading platform team) – Pays EC2 On-Demand rates for unused capacity in the interruptible ODCR, just like any standard ODCR. For example, when the analytics team uses 30 out of 60 available instances, the trading platform pays for the remaining 30 unused instances.
  • Consumer (analytics team) – Pays EC2 On-Demand rates only for the instances they actually launch and use. For example, when they use 30 instances for 4 hours, they’re charged for 30 × 4 = 120 instance-hours at the standard r7i.4xlarge On-Demand rate.

Conclusion

Amazon EC2 interruptible ODCR helps organizations optimize compute spending while maintaining operational control. Through capacity reclamation mechanisms, teams can achieve better resource utilization without compromising availability guarantees. In this post, we showed how this capability addresses real operational challenges through an example use case—enabling a trading platform to maintain their critical capacity guarantees while helping other teams access high-quality compute resources for their workloads. The predictable interruption model creates a sustainable approach to capacity sharing that benefits the entire organization.

To get started with interruptible capacity reservations, refer to EC2 Capacity Reservations User Guide. To learn more about using EC2 Auto Scaling, refer the Interruptible Capacity Reservations with EC2 Auto Scaling guide. Refer to the AWS RAM User Guide to learn more about sharing resources across your organization and the Amazon EventBridge User Guide to learn more about handling interruption notifications in your applications.

How potential performance upside with AWS Graviton helps reduce your costs further

Post Syndicated from Markus Adhiwiyogo original https://aws.amazon.com/blogs/compute/how-potential-performance-upside-with-aws-graviton-helps-reduce-your-costs-further/

Amazon Web Services (AWS) provides many mechanisms to optimize the price performance of workloads running on Amazon Elastic Compute Cloud (Amazon EC2), and the selection of the optimal infrastructure to run on can be one of the most impactful levers. When we started building the AWS Graviton processor, our goal was to optimize AWS Graviton features and capabilities to deliver a processor that provides the best price performance across a broad array of cloud workloads running on Amazon EC2. That goal continues to be our guiding principle, and today customers who adopt AWS Graviton-based EC2 instances see up to 40% better price performance on their cloud workloads when compared to equivalent non-Graviton EC2 instances. The price performance improvement is the result of both the performance improvement and the lower price in using AWS Graviton-based instances.

Price performance blends the cost of infrastructure with the amount of work you can achieve with infrastructure usage. After talking to many AWS Graviton customers, we’ve learned that the cost savings go beyond the lower AWS Graviton-based instances price. Many AWS Graviton customers told us that the performance increase from AWS Graviton allows them to consume fewer computing hours than comparable non-Graviton instances for equivalent workload throughput. In turn, this leads to further cost reduction.

The following are some of examples from our customers:

  • Pinterest achieved 47% cost savings and 38% savings on compute resources while reducing carbon emissions by 62% for its web API workload.
  • SAP powers its SAP HANA Cloud with AWS Graviton to enhance its price performance by 35% while lowering carbon impact by 45%.
  • Sprinklr improved their machine learning (ML) inference workloads’ throughput by up to 20% while reducing costs by up to 25%.

You can find more customer examples in the AWS Graviton testimonials page.

To help organizations capture similar benefits, we’ve enhanced the AWS Graviton Savings Dashboard (GSD) with new features that account for both pricing and performance improvements. In the following section we explore these new capabilities and how they can help optimize your infrastructure costs.

Understanding performance-driven cost optimization in the GSD

The GSD helps organizations identify ideal workloads for AWS Graviton migration through automated resource matching and data-driven visualizations. You can learn the GSD details and setup in this AWS compute post.

Although the dashboard has traditionally focused on calculating direct cost savings from the AWS Graviton pricing advantages, we’ve observed that customers often experience more benefits when their applications perform more efficiently on AWS Graviton processors, leading to decreased compute resource usage. To better reflect these real-world scenarios, we’ve enhanced the dashboard with new features highlighting Normalized Instance Hours (NIH) analysis capabilities so that you can model potential savings based on both pricing benefits and compute hour reductions. Although this tool helps estimate potential savings, actual performance improvements can only be determined by testing your specific workloads on AWS Graviton instances. Performance is always workload and use case specific, so we encourage you to test your AWS Graviton-based workloads using the Optimization and Performance Runbook to help you determine the actual possible NIH percent reduction.

Key dashboard components

This section outlines the following three key dashboard components: NIH reduction analysis, enhanced cost analysis visualizations, and detailed savings analysis.

NIH reduction analysis

The dashboard now features a new slider that lets you model potential cost savings by inputting the percentage reduction in NIH. Many organizations have found it challenging to calculate their total possible savings since the benefits come from two sources: the lower instance pricing of AWS Graviton and the reduced compute hours.

You can use the slider to model different cost scenarios by adjusting a theoretical NIH reduction between 0% and 40%. You can use this slider to input NIH reductions validated through your workload testing, model the combined impact of both pricing benefits and reduced compute hours, and explore different scenarios to help prioritize which workloads to test first.

Figure 1: NIH slider location

Figure 1: NIH slider location

Assume that your testing shows that your workload runs just as effectively with 15% fewer normalized instance hours on AWS Graviton. You can now plug that exact number into the slider to see your modeled savings combining both pricing differences and compute hour reductions. Although we’ve heard success stories of significant reductions from customers, we recommend starting your initial estimate with a conservative 10% baseline and adjusting based on your own testing results.

Enhanced cost analysis visualizations

The dashboard presents key visualizations that demonstrate the direct relationship between NIH reduction and cost savings. First, you see the Potential Graviton Base Savings from pricing differences alone. In the following diagram, we can observe an example of $61.54K of cost savings from migrating to equivalent AWS Graviton instances. Next, the Estimated Additional Savings Due to Performance in the same diagram shows $42.40K in savings if your performance testing confirms a 15% NIH reduction in your workload. Finally, the dashboard sums these two values into the Total Potential Graviton Savings of $103.94K. The Total Potential Graviton Savings helps visualize how both pricing benefits and any validated compute hour reductions could contribute to your overall savings.

Figure 2: Visualization with relationship between NIH reduction and cost savings

Figure 2: Visualization with relationship between NIH reduction and cost savings

The Amortized Cost Breakdown and Normalized Instance Hrs Breakdown charts in the following figure show 6-month historical trends, helping you spot patterns such as seasonal spikes or high-usage periods. These patterns can help you identify where even small efficiency improvements might yield significant savings, for example, workloads with consistently high usage or predictable peak periods that would be good candidates for testing.

Figure 3: Amortized Cost, NIH, and Total Potential Savings Breakdown charts

Figure 3: Amortized Cost, NIH, and Total Potential Savings Breakdown charts

Detailed savings analysis

Building on our commitment to help customers optimize cloud costs, we’ve enhanced the Potential Graviton Savings Details table with two columns focused on performance-based savings modeling. The Estimated Additional Savings Due to Performance column shows the modeled savings based on your chosen NIH reduction percentage, while Total Potential Graviton Savings combines this with the base pricing benefits.

Figure 4: Potential Graviton Savings Details table

Figure 4: Potential Graviton Savings Details table

As you examine your current instance family, you can observe both baseline AWS Graviton savings and these added saving opportunities clearly laid out in a comprehensive breakdown. The analysis presents your total savings potential in both dollar amounts and percentages. This allows you to build a compelling business case for migration. Although this detailed breakdown provides valuable planning insights, remember that actual savings may vary depending on your specific workload patterns, implementation approaches, and operational considerations.

Conclusion

The Graviton Savings Dashboard (GSD) serves as a powerful analytics tool that streamlines your journey to cost-effective cloud computing. The GSD provides clear visualizations and interactive features to help you understand and maximize potential savings when migrating to AWS Graviton-based instances. To further explore the new features, navigate to the GSD interactive demo, where you can model an example of potential savings using the NIH reduction slider and detailed cost breakdowns.

Ready to explore how AWS Graviton can transform your infrastructure costs? Visit the GSD page to deploy or update your GSD dashboard. Access implementation guides, such as the CFM Technical Implementation Playbook (CFM TIPs), and start optimizing your cloud spend today with the enhanced capabilities of the GSD.

Over 85,000 AWS customers have discovered the benefits of AWS Graviton, with many completing their adoptions in just hours. We have created this resource guide so that you can accelerate your AWS Graviton adoption with minimal effort and enjoy significant price performance benefits.

“What I always tell customers is one week, one application, one engineer, and see what you can do. They always are pleasantly surprised by how much progress they can make. If you’re out there and you haven’t yet moved to AWS Graviton, what are you waiting for? Let’s make it happen!”

Dave Brown, VP, AWS Compute & ML Services

Important note about performance testing
The GSD does not attempt to estimate the potential NIH percent reduction or your workload’s performance when transitioned to AWS Graviton. You can use it to perform what-if analysis of your potential savings for a projected NIH percent reduction. In the absence of this variable, GSD only considers the price delta between instance types and misses an important contributor to the overall savings potential of AWS Graviton from the performance upside. Compute performance is always workload and use case specific, so we encourage you to test your AWS Graviton-based workloads using the Optimization and Performance Runbook to help you determine the actual possible NIH percent reduction.

Optimize latency-sensitive workloads with Amazon EC2 detailed NVMe statistics

Post Syndicated from Sanjeev Malladi original https://aws.amazon.com/blogs/compute/optimize-latency-sensitive-workloads-with-amazon-ec2-detailed-nvme-statistics/

Amazon Elastic Cloud Compute (Amazon EC2) instances with locally attached NVMe storage can provide the performance needed for workloads demanding ultra-low latency and high I/O throughput. High-performance workloads, from high-frequency trading applications and in-memory databases to real-time analytics engines and AI/ML inference, need comprehensive performance tracking. Operating system tools like iostat and sar provide valuable system-level insights, and Amazon CloudWatch offers important disk IOPs and throughput measurements, but high-performance workloads can benefit from even more detailed visibility into instance store performance.

For latency-sensitive applications where every millisecond counts, enhanced performance monitoring tools provide deep visibility into storage systems, so your teams can track and analyze behavior at a 1 second granularity. This detailed insight can help your organization detect bottlenecks quickly, fine-tune application performance, and deliver reliable service.

In this post, we discuss how you can use Amazon EC2 detailed performance statistics for instance store NVMe volumes, a set of new metrics that provide per-second granularity, to provide real-time visibility into your locally attached storage performance. These statistics are similar to the Amazon EBS detailed performance statistics, providing a consistent monitoring experience across both storage types. You can access these statistics directly from your NVMe devices attached to the Amazon EC2 instance using nvme-cli or using CloudWatch agent to monitor I/O performance at the storage level. We also provide examples of how to use these statistics to identify performance bottlenecks.

Feature overview

Amazon EC2 Nitro-based instances with locally attached NVMe instance storage now offer 11 comprehensive metrics at per-second granularity. These metrics, similar to EBS volume metrics, include queue length measurements, IOPS, throughput data, and IO latency histograms for the locally attached NVMe instance storage. Additionally, they also include IO size-specific latency histograms to provide even more detailed insights into performance patterns of the local NVMe instance storage. These metrics are collected and presented separately for each individual NVMe volume available on an instance.

The statistics are presented in three main formats:

    1. Cumulative counters that track IO operations, throughput, and read/write times
    2. Real-time queue length, displaying the current value at the time of your query
    3. Latency histograms visualizing the distribution of IO operations across different latency ranges by displaying both cumulative view and IO size-specific distributions

Prerequisites

To access detailed performance statistics for local instance storage, complete the following steps:

    1. Launch a new Amazon EC2 Nitro instance or use an existing one, then connect to it using SSH or your preferred connection method.
    2. Identify the NVMe device associated with the local storage to query for the performance statistics. For example, you can run the nvme-cli command in the CLI to output all NVMe devices on the instance.
      $ sudo nvme list.

      The following is an example output of the list command that lists the NVMe devices on the instance and their volume Serial Numbers (SN; masked in the below output for privacy). In this demonstration, consider that the local storage used by your application is /dev/nvme1n1.

      Terminal output showing five NVMe devices: one EBS volume and four EC2 instance storage volumes with 3.75TB capacity each

    3. If you are using Amazon Linux 2023 version 2023.8.20250915 (or later) or Amazon Linux 2 2.0.20251014.0 (or later) you can proceed to Step 4 because nvme-cli will use the latest version. If you are using an earlier Amazon Linux version, update the nvme-cli using the following command, where 2023.8.20250915 can be replaced with the latest Amazon Linux 2023 version:
      $ sudo dnf upgrade --releasever=2023.8.20250915
    4. Run the nvme-cli, with the correct permissions, and pass the device as a parameter. You can use --help to get details on the command usage:
      $ sudo nvme amzn stats --help

      Example output:
      Command help output for 'nvme amzn stats' showing usage syntax and format options
      If you prefer output in a JSON format, you can provide the -o json parameter to the command.

      $ sudo nvme amzn stats /dev/nvme1n1 -o json

      The following output (without the -o json parameter) shows cumulative read/write operations, read/write bytes, total processing time (read and write in microseconds), and duration (in microseconds) when application attempted to exceed the instance’s IOPS/throughput limits.
      Storage performance metrics showing read operations count, total bytes, and timing statistics for an EC2 NVMe volume
      It also displays read/write I/O latency histograms, with each row representing completed I/O operations within a specific bin of time (in microseconds).
      Read latency distribution histogram showing operation counts across different microsecond ranges, with peak activity in 2048-4096 rangeWrite latency distribution histogram showing zero operations across all time ranges, indicating no write activity
      If you want to view the latency histograms across 5 different IO bands: (0, 512 Byte], (512B, 4KiB], (4KiB, 8KiB], (8KiB 32KiB], (32 KiB, MAX], you can provide --details or -d parameter to the command:

      $ sudo nvme amzn stats -d /dev/nvme1n

      The following image is an excerpt of the above command’s output, showing the additional latency histograms (read and write) of the 5 different IO bands.
      Dual read/write I/O latency histogram analyzing small block operations from 0-512 bytes with peak at 4096-8192 rangePerformance analysis histogram showing I/O patterns for 512-4K blocks with significant activity in 512-1024 rangeDual histogram showing I/O latency patterns for 4K-8K block operations with concentrated activity at 4096-8192Performance analysis histogram displaying I/O patterns for 8K-32K blocks with peak activity in 4096-8192 rangeComprehensive I/O latency histogram analyzing largest block sizes from 32K to maximum with concentrated activity in 4096-8192

You can run the stats command at a per second granularity. You can also write scripts to pull the stats at a desired interval (every second or any other duration) with each subsequent output reflecting the updated cumulative totals for the metrics. Calculating the difference in the statistics across the last two outputs allows you to derive insight into the instance storage profile during the interval. Below is a sample script you can use to pull the stats at a default interval of 1 second or at your desired interval.

#!/bin/bash 
# interval of 1 second 
INTERVAL=${1:-1} 
while true; do 
	echo "=== $(date) ===" 
	sudo nvme amzn stats /dev/nvme1 || break 
	echo 
	sleep $INTERVAL 
done

You can save this script, make it executable and run it at either the default 1-second interval or provide a custom interval when executing the script. For example, if you saved the script as nvme_stats.sh, you could use the following commands to make it executable and run to get the output at the default 1-second interval (assuming you are in the same directory as that of nvme_stats.sh).

chmod +x nvme_stats.sh
./nvme_stats.sh

If, for instance, you want to get the output at every 5 seconds, you can use the command below (after making the script executable)

./nvme_stats.sh 5

You can also integrate with CloudWatch using CloudWatch agent to collect and publish these statistics for historical tracking, trend visualization through dashboards, and performance-based alerts to correlate with application metrics and automated notifications for performance issues.

Deriving insights from the Amazon EC2 instance store NVMe detailed performance statistics

Similar to EBS detailed performance statistics, you can use Amazon EC2 instance store NVMe statistics to troubleshoot various workload performance issues. As mentioned in the preceding section, you can also use the detailed statistics to view I/O latency histograms to observe the spread of I/O latency within the period. You can use the read/write operations and time spent statistics to calculate the average latency. The detailed statistics show the average latency at per-second granularity.

The next two example scenarios demonstrate key performance analysis using the statistics. In Scenario 1, we will use the EC2 Instance Local Storage Performance Exceeded (us) metric to check if I/O demands exceed instance storage capabilities, helping with instance right-sizing for sufficient I/O application performance. In Scenario 2, we will use IO-size specific histograms (using --details) to diagnose how large block writes affect subsequent read performance – an issue typically hidden by traditional monitoring tools’ aggregated metrics across all IO sizes.

Scenario 1: Identifying when applications exceed instance storage performance limits

Understanding whether your application’s I/O demands exceed your instance store volumes’ capabilities is important for performance troubleshooting. When applications generate I/O workloads that consistently attempt to exceed the IOPS and throughput limits of specific Amazon EC2 instance types, you’ll experience increased latency and degraded performance. The EC2 Instance Local Storage Performance Exceeded (us) metric helps identify these scenarios by showing the duration (in microseconds) when workloads exceeded supported instance performance. A non-zero value or increasing count between snapshots indicates your current instance size or type may not provide sufficient I/O performance for your application.

The following section shows how to identify if an application is sending more IOPS than the instance’s local storage can support.

The example scenario: An application on an i3en.xlarge instance shows elevated write latency of >1ms. You want to determine if the application’s workload is exceeding the instance’s NVMe volume supported performance.

    1. Select the Instance Storage NVMe device you want to analyze – Identify the instance you want to analyze for the application experiencing elevated latency.
    2. Identify the NVMe device – Use the following nvme-cli command, and identify the NVMe device associated with that instance storage.
      $ sudo nvme list

      Example scenario: We used the list and identified /dev/nvme1n1 as the NVMe device associated with the i3en.xlarge instance that is running the application which is currently seeing elevated write latency >1ms (while read latency is <50us as per normal conditions), so now we want to. analyze it.

    3. Collect statistics for the device at a single point in time or at desired intervals – Collect the detailed performance statistics using the nvme-cli command or use the sample script provided in previous section to capture statistics at the desired intervals, if needed.
      $ sudo nvme amzn stats /dev/nvme1n1

      Example scenario: We choose to collect the statistics only once after noticing elevated write latency of the application.

    4. Analyze the statistics to check if the application demands more than the supported performance of the instance storage – Confirm existence of overall I/O latency degradation by comparing two sets of read/write I/O latency histograms taken some time apart.Example scenario: The following output shows Read IO histogram of the NVMe local instance storage taken 40 seconds apart with no read IO latency issues (as normal read latency for this workload is < 50 us).

      Metric captured at time T:
      AWS EC2 storage performance histogram showing read latency distribution, peak at 16-32 microsecond bucket
      Metric captured at time T+40s:
      AWS EC2 storage performance data showing increased read latency concentration in 16-32 microsecond bucket
      The following output shows Write IO histogram taken 40 seconds apart. We can discern that many write IOs fall into the 1ms – 2ms latency range, which is not expected for this application.
      Metric captured at time T:
      AWS EC2 storage write performance data showing majority of operations between 1-2ms latency
      Metric captured at time T+40s:
      AWS EC2 storage performance metrics showing increased write operations clustered in 1-2ms latency range

    5. Analyze the EC2 Instance Local Storage Performance Exceeded (us) metric which shows total time (in microseconds) IOPS requests exceed volume limits. Ideally, the incremental count of this metric between two snapshot times should be minimal, as any value above 0 indicates that the workload demanded more IOPS than the volume could deliver.Example scenario: Comparing metrics 40 seconds apart shows that for more than 34 seconds, the application’s IOPS demands surpassed the IOPS supported by the local instance storage. This explains elevated write latency: excess IOPS above what the underlying storage can physically handle queue the operations, increasing wait times. This indicates that the i3en.xlarge instance chosen to run this application cannot meet the application’s performance requirements, suggesting either upgrading to a larger instance size or re-evaluating the instance type itself.
      Metric captured at time T:
      EC2 Instance Local Storage Performance exceeded output of nvme-cli for the described scenario at time T
      Metric captured at time T+40s:
      EC2 Instance Local Storage Performance exceeded output of nvme-cli for the described scenario at time T+40 with increased count of metric

It’s important to have the right instance size to avoid performance bottlenecks to your application. Refer to the Amazon EC2 instance documentation for more information on the different instances and their storage size.

Scenario 2: Identifying the block size causing elevated latency in your applications

Many storage performance issues arise from complex interactions between read and write operations with different I/O sizes, which traditional system-level monitoring tools like iostat or sar cannot effectively diagnose due to their aggregated metrics across all I/O sizes. EC2 instance store NVMe detailed performance statistics solves this by providing I/O-size specific latency histograms through the --details option in NVMe CLI. These histograms show latency data for different I/O size ranges: (0, 512 Byte], (512B, 4KiB], (4KiB, 8KiB], (8KiB, 32KiB], (32KiB, MAX], for a more precise correlation between application workload patterns and I/O size-specific latency metrics for targeted optimizations.

In this example scenario, your application performs small reads (typically <=4KiB, like metadata read) followed by large writes (>=32KiB) and shows unexpectedly high read latency. This common issue occurs when large writes impact subsequent read operations’ performance, creating a cascading effect on overall I/O performance.

    1. Gather read and write IO latency by size ranges – Use the NVMe CLI with the --details option to gather read and write IO latency by size ranges:
      $ sudo nvme amzn stats /dev/nvme1n1 --details

    2. Confirm existence of overall IO latency degradation – In the example scenario, examining overall IO latency, both read (left) and write (right) operations are showing higher than expected latency.
      NVMe storage read latency histogram highlighting concentrated IO operations in 4K-16K microsecond rangeNVMe storage write latency histogram highlighting concentrated IO operations in 8-32K microsecond range
    3. Examine the output for patterns across different IO size bands – Analyzing latency by operation sizes shows small read operations (512 bytes to 4K), typically fast, are experiencing unexpected latency spikes while large writes (32K+) show significant delays. Small reads should theoretically maintain good performance regardless of other I/O activities.
      NVMe storage read/write latency histogram highlighting concentrated IO operations in 8-16K microsecond range for IO band of 512 - 4KNVMe storage read/write latency histogram highlighting concentrated IO operations in 8-16K microsecond range in IO band 32K and above
      The observed pattern indicates that the backed-up large write operations create system-wide congestion, affecting all I/O operations of types and sizes. Despite the storage system’s capability to handle small reads efficiently, the queued large writes slow down both read and write operations at the application level.

Based on this analysis, we can implement several targeted optimizations to the application, like using smaller block sizes for write operations when possible, or batching smaller writes instead of performing large single writes.

Clean up

If you created an Amazon EC2 instance with NVMe volume for this exercise, then terminate and delete the appropriate instance to avoid future costs.

Conclusion

Amazon EC2 detailed performance statistics for instance store NVMe volumes provide real-time, sub-minute storage performance monitoring, similar to the detailed performance statistics available for Amazon EBS volumes. This offers consistent monitoring experience across both storage types, with additional IO-size based latency histograms for instance storage for better optimization of I/O patterns, and more effective troubleshooting.

To learn more about Amazon EC2 instance store NVMe volumes, optimization techniques for latency-sensitive workloads or other Amazon EC2 related topics, visit the Amazon EC2 documentation page or explore our other AWS Storage Blog posts on performance optimization.

We’d love to hear how you’re using these statistics to enhance your workloads, or if you have any questions, in the comments section below.