Tag Archives: Amazon OpenSearch Service

Introducing the Amazon OpenSearch Lens for the AWS Well-Architected Framework

Post Syndicated from Muslim Abu-Taha original https://aws.amazon.com/blogs/big-data/introducing-the-amazon-opensearch-lens-for-the-aws-well-architected-framework/

Earlier this year, we released the Amazon OpenSearch Service Lens, an AWS Well-Architected whitepaper. The AWS Well-Architected Framework provides a consistent approach for evaluating architectures and implementing scalable designs. Using this framework, the Amazon OpenSearch Service Lens outlines how to perform AWS Well-Architected reviews to assess and identify technical risks in your OpenSearch Service deployments.

In this post, we show you how to use the Amazon OpenSearch Service Lens to evaluate your OpenSearch Service workloads against architectural best practices.

Understanding the AWS Well-Architected Framework

At AWS, a well-architected cloud environment is fundamental to helping you achieve your business outcomes. The AWS Well-Architected Framework represents the collective experience of AWS from working with organizations across industries, distilled into a structured approach for evaluating architectures and implementing designs that scale over time. The AWS Well-Architected Framework is built on six pillars: Operational Excellence, Security, Reliability, Performance Efficiency, Cost Optimization, and Sustainability. Using the Framework, cloud architects, system builders, engineers, and developers can build secure, high performance, resilient, and efficient infrastructure for their applications and workloads.

OpenSearch Service Lens

The OpenSearch Service Lens is a collection of customer-proven design principles and best practices to help you adopt a cloud-native approach to using Amazon OpenSearch Service. These recommendations are based on insights that AWS has gathered from customers, AWS Partners, the community, and our own AWS OpenSearch technical specialist communities.

The OpenSearch Service Lens extends the AWS Well-Architected Framework to help you address critical architectural questions specific to Amazon OpenSearch workloads, for example:

  • How do you size and configure Amazon OpenSearch Service domains for optimal performance?
  • What data retention and lifecycle management strategies help balance cost and accessibility?
  • How do you implement security controls that protect sensitive data while maintaining search functionality?
  • What operational practices ensure reliable search experiences as your data volumes grow?

The OpenSearch Service Lens joins a collection of AWS Well-Architected Lenses that focus on specialized workloads such as the Internet of Things (IoT), games, artificial intelligence (AI) and machine learning (ML), SAP, and serverless technology.

The lens highlights some of the most common areas for assessment and improvement. It is designed to align with and provide insights across the six pillars of the AWS Well-Architected Framework:

  • Operational excellence focuses on running and monitoring systems to deliver business value, and continually improving processes and procedures. This topic includes the ability to support development and run workloads effectively, gaining insights into their operations, and continuously improve supporting processes to deliver business value.
  • Security focuses on protecting your data and systems. This addresses implementing fine-grained access control for users and applications, securing domain access through encryption and network controls, detecting and mitigating vulnerabilities, reducing potential attack surfaces, and protecting sensitive data.
  • Reliability focuses on ensuring an end user environment performs correctly and consistently when it’s expected to. This topic includes implementing automatic disaster recovery mechanisms, designing multi-Availability Zone deployments for high availability, scaling domain capacity to meet demand, and using automation for operational tasks to reduce human error. It also covers implementing backup and restore strategies, managing cluster state, and setting up monitoring and alerting to maintain service performance and availability.
  • Performance efficiency focuses on using Amazon OpenSearch Service resources effectively. This includes selecting appropriate instance types and storage options based on your workload requirements, implementing performance monitoring and optimization strategies, and using OpenSearch Service features to reduce operational overhead. It also covers tuning domain configurations, managing data indexing patterns, and optimizing search and analytics queries to achieve the best possible performance while maintaining cost efficiency.
  • Cost optimization focuses on managing expenses effectively. This topic addresses implementing cost allocation tags to track domain expenses by workload, selecting appropriate instance types and storage options based on your needs, and choosing cost-effective payment options such as Reserved Instances for predictable workloads. It also covers using UltraWarm and cold storage tiers for infrequently accessed data, implementing index lifecycle policies to manage storage costs, and monitoring usage patterns to rightsize domains and optimize performance-to-cost ratios.
  • Sustainability focuses on minimizing the environmental impacts of running cloud workloads. OpenSearch topics addresses implementing efficient domain sizing strategies, selecting instance types with the best performance-to-energy ratio, optimizing retention policies and using different storage tiers to reduce the active compute footprint.

By applying this lens to your Amazon OpenSearch Service workloads, you gain insights that go beyond general architectural principles to address characteristics of search and analytics implementations. The OpenSearch Service Lens provides a consistent framework for making architectural decisions aligned with AWS best practices for designing a new Amazon OpenSearch Service architecture or optimizing an existing deployment.

Getting started with the OpenSearch Lens

To get started with the Amazon OpenSearch Service Lens, review the six pillars of the AWS Well-Architected Framework: Operational Excellence, Security, Reliability, Performance Efficiency, Cost Optimization, and Sustainability.

Then, sign in to the AWS Management Console and open the AWS Well-Architected Tool. Navigate to Custom Lenses and import the Amazon OpenSearch Service Lens. After importing the lens, you can use the specialized questionnaires to evaluate your OpenSearch Service workloads against best practices, and once you complete the questionnaire, you will get insightful feedback.

Next, plan architecture reviews with your team to evaluate your Amazon OpenSearch Service domains using the lens criteria. Document your assessment results, including what works well and where you can improve your deployment. For help understanding the Amazon OpenSearch Service Lens questions, refer to the lens documentation.

If you have an AWS Support plan, you can request help with your architecture review. The OpenSearch Service Lens questions aim to guide your architectural decisions, not test your knowledge. Focus on understanding the architectural principles behind each question. After completing your assessment, create a prioritized improvement plan that addresses findings that could affect your workload performance, data durability, and cost efficiency. For help implementing these improvements, you can work with AWS Professional Services or AWS Partners who specialize in Amazon OpenSearch Service.

Conclusion and next steps

The Amazon OpenSearch Service Lens provides actionable guidance to help you build well-architected search and analytics workloads aligned with your business requirements. Start by accessing the AWS Well-Architected Tool and applying this lens to your OpenSearch Service domains. Make architectural reviews a regular part of your development process. Consider sharing your experiences with the AWS community to help others improve their OpenSearch Service implementations.

You can find more information on AWS Well-Architected Lenses in the AWS Well-Architected Tool User Guide. We encourage you to incorporate this specialized guidance into your architectural reviews and use it to drive continuous improvement in your search and analytics workloads on AWS.

AWS regularly updates the Amazon OpenSearch Service Lens to reflect new service capabilities and architectural best practices. These updates help you take advantage of the latest improvements in Amazon OpenSearch Service while maintaining architectural excellence.

To learn more about Amazon OpenSearch Service, including customer success stories and additional resources, visit Amazon OpenSearch Service page.


About the authors

Muslim Abu-Taha

Muslim Abu-Taha

Muslim is the Senior Worldwide Specialist Solutions Architect for Amazon OpenSearch located in Dubai, UAE. He works with customers across Europe, the Middle East and Africa to support them on their journeys adopting and scaling AWS OpenSeach workloads.

Shih-Yong Wang

Shih-Yong Wang

Shih-Yong is a Solutions Architect at AWS in Taiwan. He utilizes over twenty years of IT expertise to empower clients across diverse industries. By strategically leveraging AWS services, he helps foster business value and creates limitless opportunities for innovation.


Contributors

The authors would like to thank the following people for their invaluable help in developing this new OpenSearch Lens for the AWS Well-Architected Framework: Muslim Abu-Taha, Senior Worldwide Specialist Solutions Architect for Amazon OpenSearch; Shih-Yong Wang, Manager, Solutions Architecture; Ankush Agarwal, Solutions Architect; and Jun-Tin Yeh, Cloud Optimization Success Solutions Architect.

The authors would also like to thank the following people for their contributions to technical reviews: Cedric Pelvet, Principal OpenSearch Solutions Architect; Hajer Bouafif, Senior OpenSearch Solutions Architect; Francisco Losada, OpenSearch Solutions Architect; Bharav Patel, OpenSearch Solutions Architect; and Praveen Prasad, Senior Specialist Technical Account Manager.

Analyzing Amazon EC2 Spot instance interruptions by using event-driven architecture

Post Syndicated from Shekhar Shrinivasan original https://aws.amazon.com/blogs/big-data/analyzing-amazon-ec2-spot-instance-interruptions-by-using-event-driven-architecture/

Amazon Elastic Compute Cloud (Amazon EC2) Spot Instances offer significant cost savings of up to 90% compared to On-Demand pricing, making them attractive for cost-conscious workloads. However, when using Spot Instances within AWS Auto Scaling Groups (ASGs), their unpredictable interruptions create operational challenges. Without proper visibility into interruption patterns, teams struggle to optimize capacity planning, implement effective fallback mechanisms, and make informed decisions about workload placement across availability zones and instance types.

This challenge can be addressed through a custom event-driven monitoring and analytics dashboard that provides near real-time visibility into Spot Instance interruptions specifically for ASG-managed instances. For the remainder of this document, we’ll refer to this custom solution as “Spot Interruption Insights” for Auto Scaling Groups.

In this post, you’ll learn how to build this comprehensive monitoring solution step-by-step. You’ll gain practical experience designing an event-driven pipeline, implementing data processing workflows, and creating insightful dashboards that help you track interruption trends, optimize ASG configurations, and improve the resilience of your Spot Instance workloads.

Solution overview

The architecture uses an event-driven approach utilizing AWS native services for robust spot instance interruption monitoring.

The solution uses Amazon EventBridge to capture interruption events, Amazon Simple Queue Service (Amazon SQS) for reliable message queuing, AWS Lambda for data processing, and Amazon OpenSearch Service for storage and visualization of interruption patterns.

  1. EC2 Spot interruption notices are captured via an Amazon EventBridge rule.
  2. The notices are routed to an SQS queue for reliable message handling.
  3. A Lambda function processes the events, fetching EC2 instance metadata and AWS Auto Scaling Group (ASG) details by making optimized batch calls to the EC2 and Auto Scaling APIs. This design minimizes throttling risks on the control plane APIs, ensuring scalability. The Lambda function is configured with batching and concurrency limits to prevent overwhelming the API endpoints and the OpenSearch Service bulk indexing process.
  4. After processing, events are bulk-indexed into Amazon OpenSearch Service, enabling near real-time visibility and analytics.

A Dead Letter Queue (DLQ) ensures no data is lost in case of failures, while AWS Identity and Access Management (IAM) roles enforce least-privilege access between all components.

The OpenSearch Service domain is deployed within the private subnets of an Amazon VPC, ensuring it is not publicly accessible.

  1. Access to OpenSearch Dashboards is routed through an Application Load Balancer (ALB) configured with an HTTPS listener,
  2. ALB forwards traffic to an NGINX proxy running on EC2 instances in an Auto Scaling group. This setup provides secure and scalable access.
  3. Authentication and authorization are enforced using OpenSearch Service’s internal user database, ensuring that only authorized users can access the dashboards.

OpenSearch Dashboards visualize interruption metrics, delivering actionable insights to support effective capacity planning and workload placement.

Extensibility and alternative analytics tools

While this solution uses Amazon OpenSearch Service for storing and visualizing Spot Interruption data, the architecture is flexible and can be extended to support other analytics and observability platforms. You can modify the Lambda function to forward data to tools such as Amazon Quick Sight, Amazon Timestream, Amazon Redshift, or external services depending on your analytics and compliance needs. This enables teams to use their preferred tooling for building visualizations, setting alerts, or integrating with existing dashboards.

What you’ll build

By the end of this post, you’ll have a complete Spot Interruption monitoring system as seen in the following screenshot that automatically captures EC2 Spot Instance interruption events from your Auto Scaling Groups and presents them through interactive dashboards. Your solution will include real-time visualizations showing interruption patterns by availability zone, instance types, and time periods, along with ASG-specific metrics that help you identify optimization opportunities.

The sections of this post walk you through the step-by-step implementation of this solution, from deployment to setting up the event-driven architecture to configuring the analytics dashboards. Remember that you can deploy and customize this solution for your environment.

Prerequisites

You must have access to an AWS account with enough privileges to create and manage the AWS resources discussed in this blog post.You must also have the following software/components installed on your device:

Note: This application utilizes multiple AWS services, and there are associated costs beyond the Free Tier usage. Refer to the AWS Pricing page for specific details. You are accountable for any incurred AWS costs. This example solution does not imply any warranty.

Deployment instructions

Create a new directory, navigate to that directory in a terminal and clone the GitHub repository:

git clone https://github.com/aws-samples/sample-spot-interruption-insights

Change directory to the solution directory:

cd sample-spot-interruption-insights

Checklist for deployment

This section lists the setup and configurations that are required before you deploy the solution stack by using AWS SAM.

If you don’t have a VPC, Subnets, NAT Gateway already created and configured you can follow the steps mentioned in the Amazon VPC documentation to create the necessary resources.

  1. VPC Created – Ensure a VPC exists with DNS hostnames and DNS resolution enabled. You will need the VPC ID during deployment
  2. Public Subnets (2 or more) – Configure two or more public subnet IDs from different Availability Zones.
  3. Private Subnets (2 or more) – Configure two or more private subnet IDs from different Availability Zones.
  4. Outbound Internet Access for Private Subnets – Ensure NAT Gateway access as nginx proxy will be installed on EC2 instance in private subnet. Refer to Example: VPC with servers in private subnets and NAT for more information on setting up NAT for instances in private subnets.
  5. ALB Access – CIDR IP range allowed to access ALB (such as, `1.2.3.4/32`). This is for accessing the dashboard.
  6. Certificate ARN for ALB HTTPS Listener – To configure HTTPS listener. Certificate (can be self-signed) for HTTPS port of the load balancer. Refer to Prerequisites for importing ACM certificates for more information on importing self-signed certificate into AWS Certificate Manager (ACM)
  7. OpenSearch Service-Linked Role – Before deploying this template, ensure the AWS OpenSearch service-linked role exists in your account by running:
    aws iam create-service-linked-role --aws-service-name es.amazonaws.com

    Note:

    • This command only needs to be run once per AWS account.
    • If the role already exists, you’ll see an error message that can be safely ignored.
    • This role allows Amazon OpenSearch Service to manage network interfaces in your VPC.
    • Without this role, deployments that place OpenSearch Service domains in a VPC will fail with the error: “Before you can proceed, you must enable a service-linked role to give Amazon OpenSearch Service permissions to access your VPC.”
    • The service-linked role is named "AWSServiceRoleForAmazonOpenSearchService" and is managed by AWS.
  8. AMIId – Valid EC2 AMI ID for the region. Note:- This solution is designed to work exclusively with AMIs that use the DNF package manager. Use the latest Amazon Linux 2023 AMI for optimal compatibility and security.

    The following AMIs are confirmed compatible with this solution:

    • Amazon Linux 2023
    • Fedora (35 and newer)
    • RHEL 8 and newer
    • CentOS Stream 8 and newer
    • Oracle Linux 8 and newer

Build and deploy the solution – From the command line, use AWS SAM to build and deploy the AWS resources as specified in the template.yml file.

sam build
sam deploy --guided

During the prompts: Fill-out the following parameters:

  • Stack Name: {Enter your preferred stack name}
  • AWS Region: {Enter your preferred region code}
  • Parameter DomainName: {Enter the name for your new OpenSearch Service domain where the index will be created and data will be pushed for analytics. This will create a new OpenSearch domain with the name you specify – Preferably keep short domain name}
  • MasterUsername: {Admin username to login to the OpenSearch dashboard}
  • MasterUserPassword: { Must contain lowercase, uppercase, numbers, and special characters (!@#$%^&*). Minimum 12 characters recommended. Avoid common passwords (Password123!, Admin@2024 and more) as these may cause deployment failures due to security validation checks.}
  • IndexName: {OpenSearch Index name where Spot interrupted instance related data will be pushed}
  • EventRuleName: {Amazon EventBridge rule name to capture EC2 Spot interruption notices}
  • CustomEventRuleName: {Amazon EventBridge custom rule name to capture EC2 Spot interruption notices. This will be used for verifying the solution}
  • TargetQueueName: {EventBridge Rule target SQS name}
  • SQSDLQQueueName: {Target SQS Dead Letter Queue name}
  • LambdaDLQQueueName: {Lambda Dead Letter Queue name}
  • VPCId: {Enter the VPCId where the resources will be deployed}
  • PublicSubnetIds: {Enter 2 or more Public SubnetIDs separated by comma}
  • PrivateSubnetIds: {Enter 2 or more Private SubnetIDs separated by comma}
  • RestrictedIPCidr: {IP address/CIDR for restricting ALB access in CIDR format (such as 10.2.3.4/32)}
  • CertificateArn: {Certificate ARN for configuring ALB HTTPS Listener}
  • AMIId: {Valid EC2 AMI ID for the region}
  • Confirm changes before deploy: Y
  • Allow SAM CLI IAM role creation: Y
  • Disable rollback: N
  • Save arguments to configuration file: Y
  • SAM configuration file: {Press enter to use default name}
  • SAM configuration environment: {Press enter to use default name}

Note: The complete solution may take approximately 15-20 minutes to deploy. After the deployment is complete, there are a few manual steps that need to be performed to ensure the solution functions as expected.

Post deployment instructions

The following steps need to be performed in OpenSearch Dashboards after logging in. Get the DNS Name of the Application Load Balancer endpoint from the deployment output section of the CloudFormation stack or the ALB console. Access the OpenSearch dashboards using the ALB DNS name as follows –

https://[ALB-DNS-NAME]/_dashboards

You will be redirected to the OpenSearch Dashboards login page. Log in using the MasterUsername and MasterUserPassword you specified during deployment.

If this is the first time you are logging in then you may see a Welcome screen.

  1. Choose ‘Explore on my own’ on the Welcome screen.
  2. Choose ‘Dismiss’ on the next screen.
  3. If the ‘Select your tenant’ dialog appears with ‘Global’ preselected, Choose ‘Confirm’. Otherwise, select ‘Global’ first and then and choose ‘Confirm’.

Create index and attribute mapping

This section lists the required steps to create the index and attribute mapping.

  1. On the Home screen select the Hamburger Menu icon () on the top left
  2. Select ‘Dev Tools’ at the bottom of the menu.
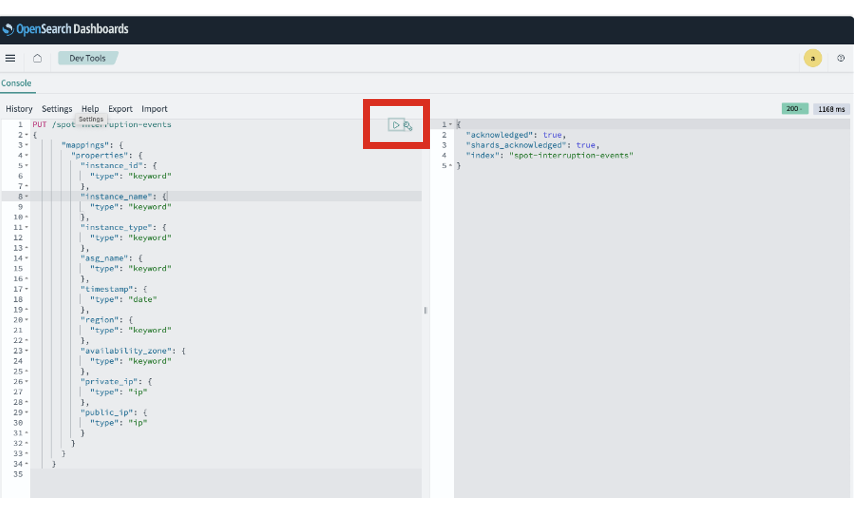
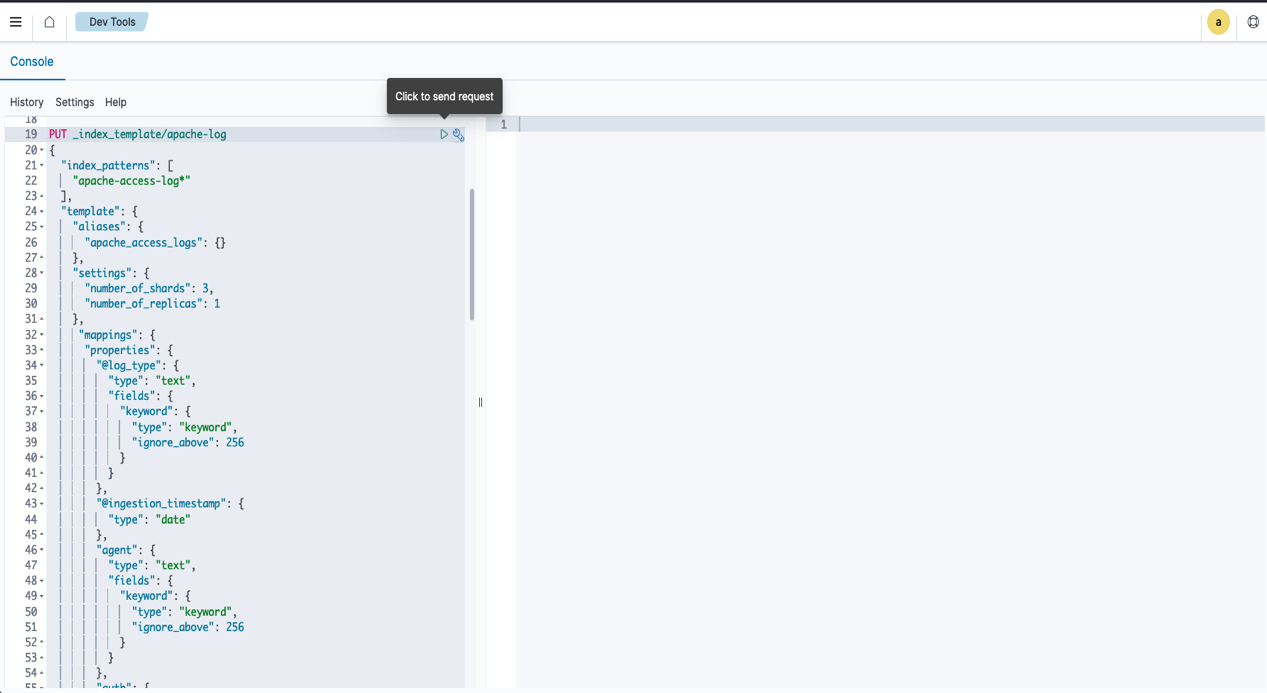
  3. On the dev tools console, paste the following PUT command and execute the request by choosing ‘Click to send request’.

    Note The index name should match what you entered during the deployment. Change the index name accordingly before creating the index.

    PUT /<YOUR-INDEX-NAME-SPECIFIED-DURING-DEPLOYMENT>
            {
                "mappings": {
                    "properties": {
                    "instance_id": {
                        "type": "keyword"
                    },
                    "instance_name": {
                        "type": "keyword"
                    },
                    "instance_type": {
                        "type": "keyword"
                    },
                    "asg_name": {
                        "type": "keyword"
                    },
                    "timestamp": {
                        "type": "date"
                    },
                    "region": {
                        "type": "keyword"
                    },
                    "availability_zone": {
                        "type": "keyword"
                    },
                    "private_ip": {
                        "type": "ip"
                    },
                    "public_ip": {
                        "type": "ip"
                    }
                    }
                }
            }

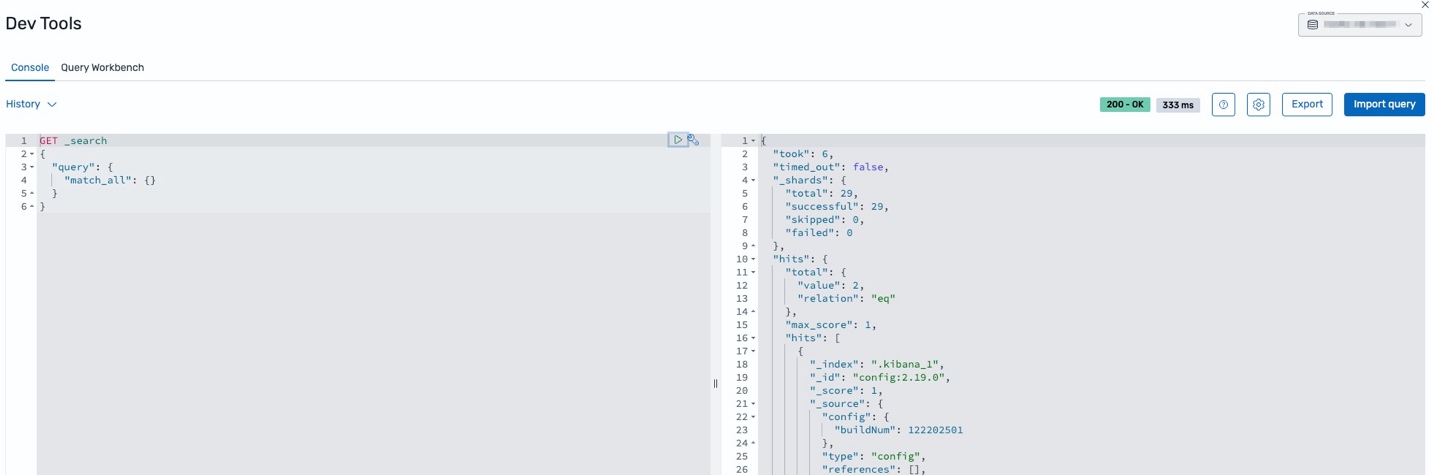
    The following is a screenshot of this command in Dev Tools.

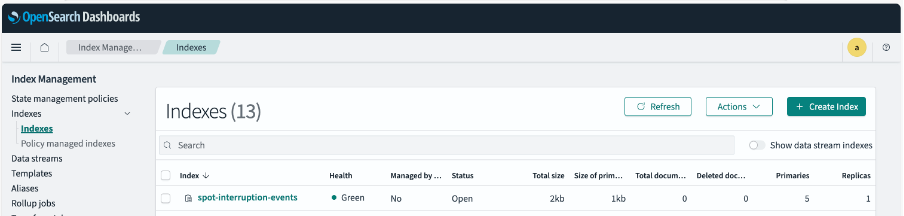
  4. Confirm that the index was created successfully.

Create index pattern

This section lists the required steps to create the index pattern

  1. Access the Hamburger Menu icon on the top left.
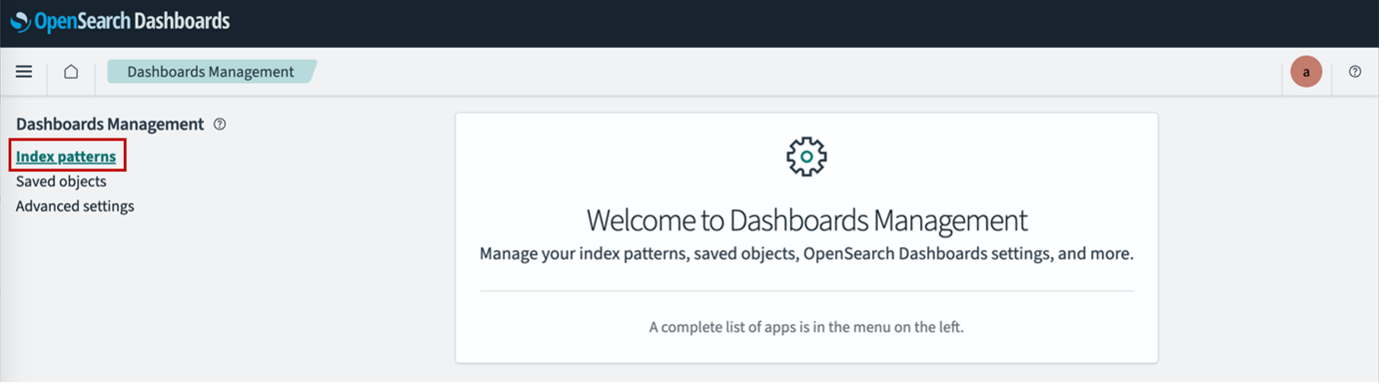
  2. Select ‘Dashboard Management’ from the bottom of the menu.
  3. Choose ‘Index Patterns’
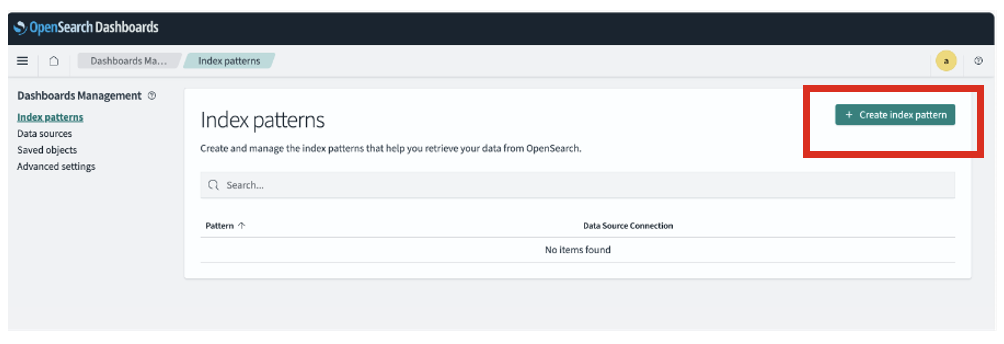
  4. Choose “Create Index Pattern”
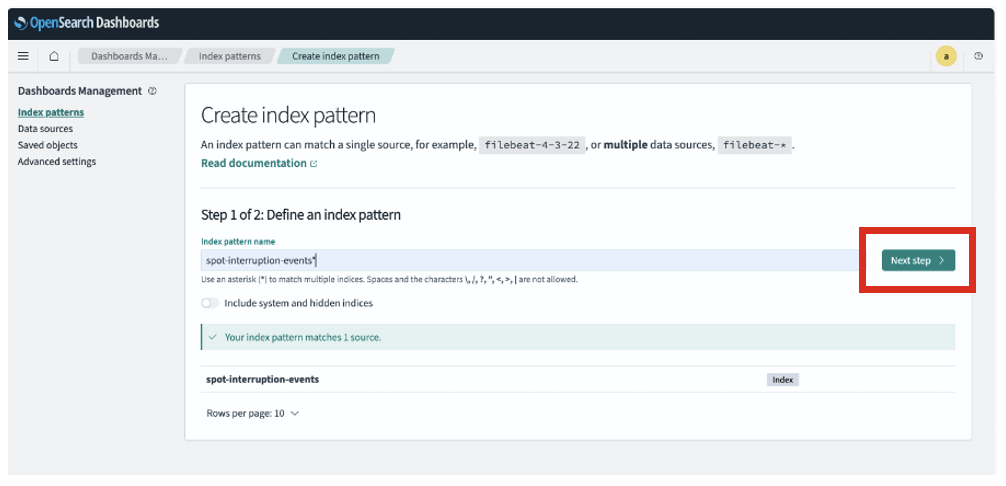
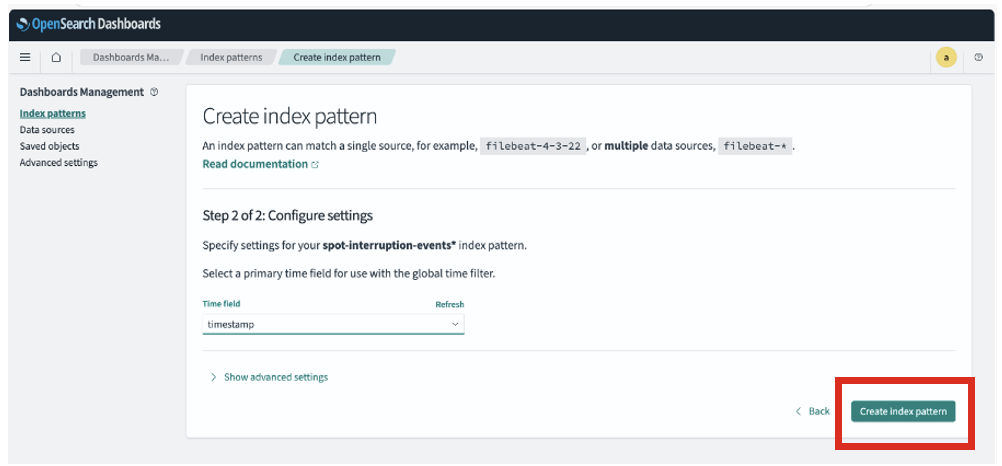
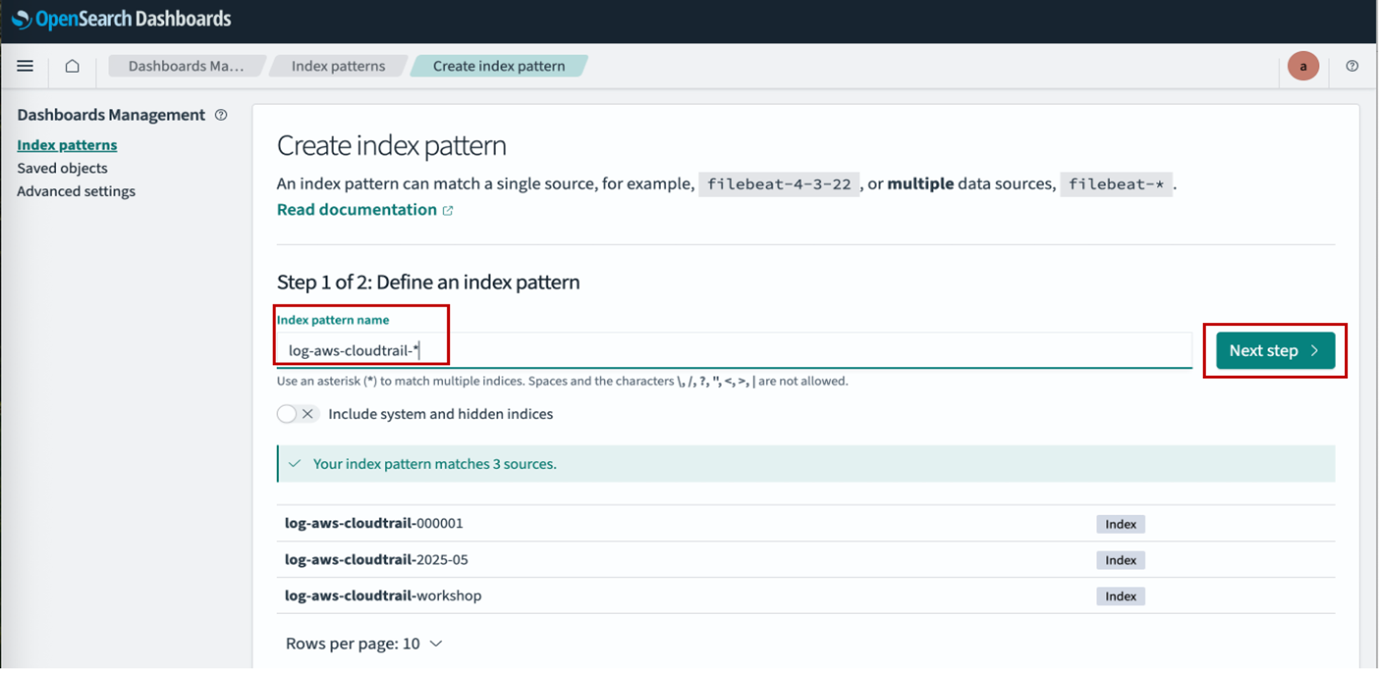
  5. Enter the Index pattern name and choose “Next step”.
    The index pattern name should be the index name you entered during the deployment followed by an asterisk. See the following screenshot for reference.

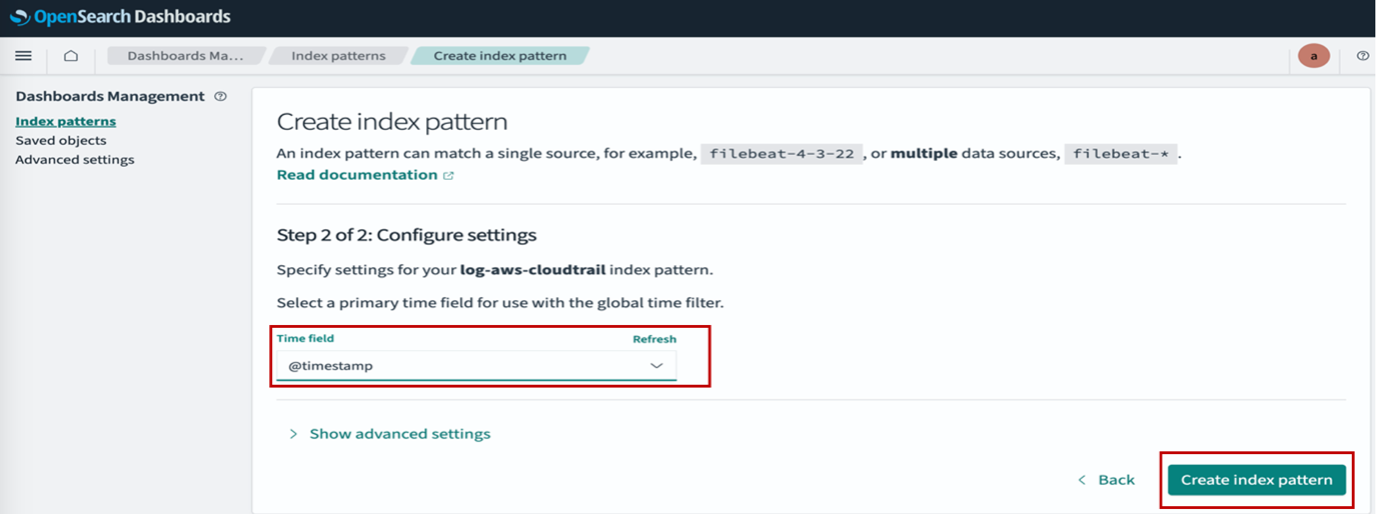
  6. Select ‘timestamp’ in primary Time field and choose ‘Create index pattern’
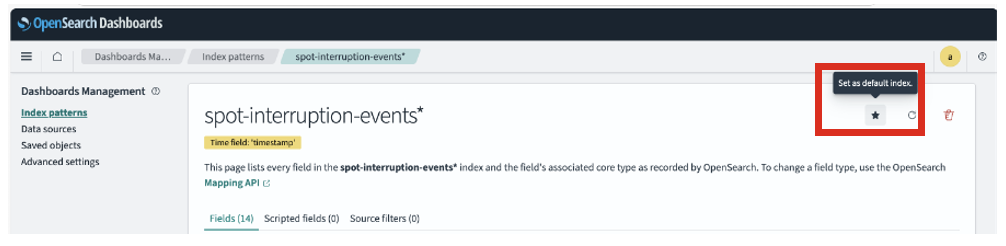
  7. Choose the star icon to make the index pattern default

Configure Lambda with required access for new index

In this section you will create a role in OpenSearch Service dashboards and will map Lambda execution role to the same to perform operations on the new index.

  1. Navigate to the Lambda console
  2. Search for the function beginning with your OpenSearch Service domain name.
  3. In the function details, go to Configuration > Permissions
  4. Choose the Role Name in the Execution Role section.
  5. Copy the Lambda execution role ARN from this function which handles Spot interruption events.
  6. Access the Hamburger Menu icon on the top left and select ‘Security’ from the bottom of the menu.
  7. Now select the ‘Roles’ menu option under ‘Security’ menu and then select ‘Create Role’
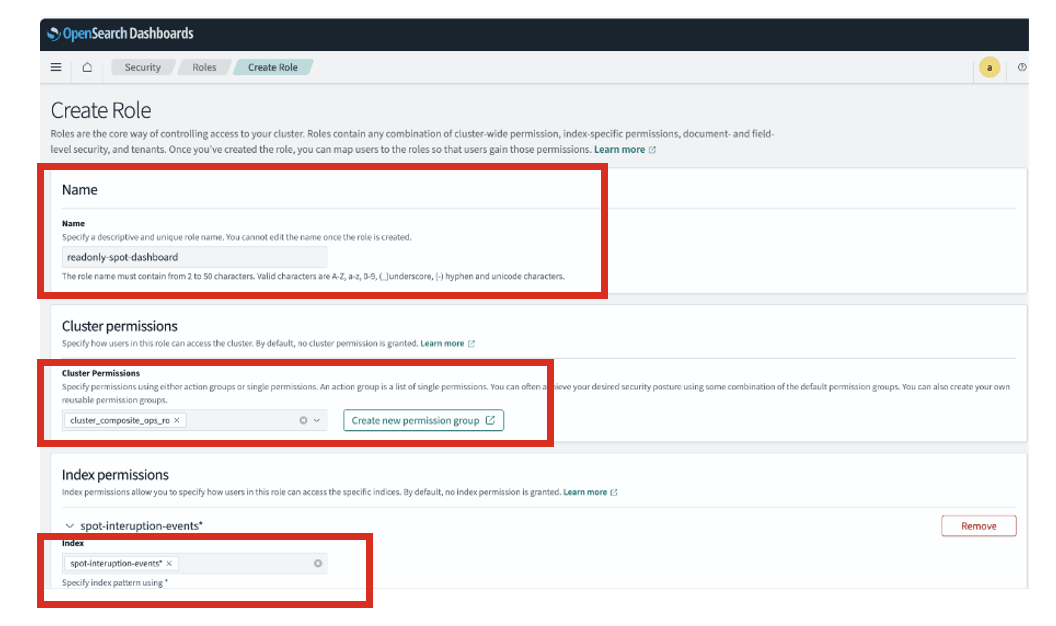
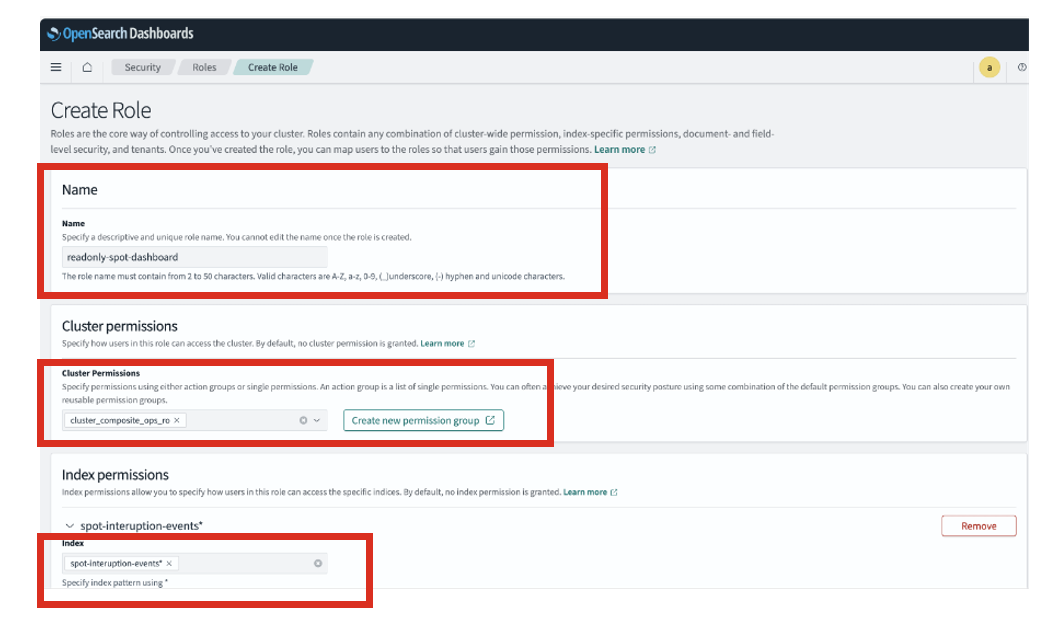
    • Enter a role name and set Cluster Permissions to “cluster_composite_ops_ro“.
    • For Index Permissions, select the index pattern name created during deployment.

    See the following screenshot for reference.

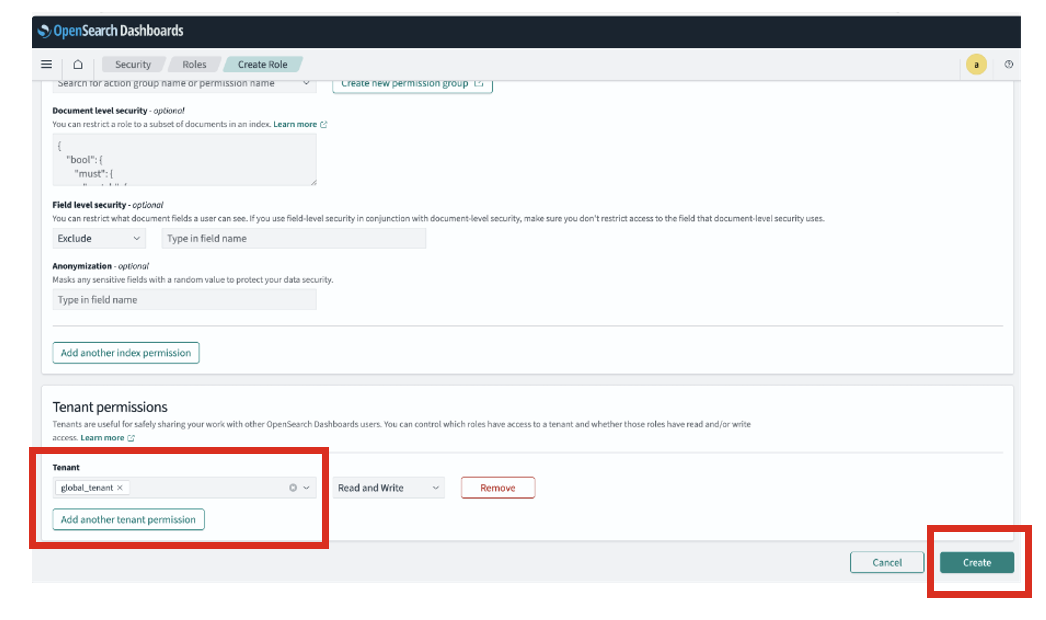
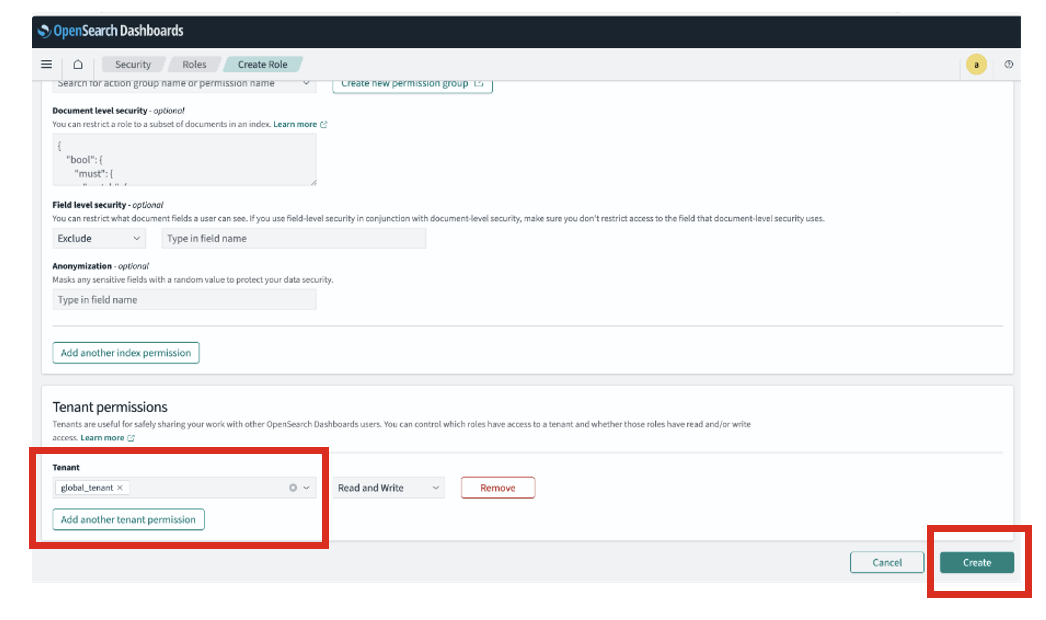
  8. Set the Tenant Permissions to “global_tenant” as seen in the image and Choose “Create”.

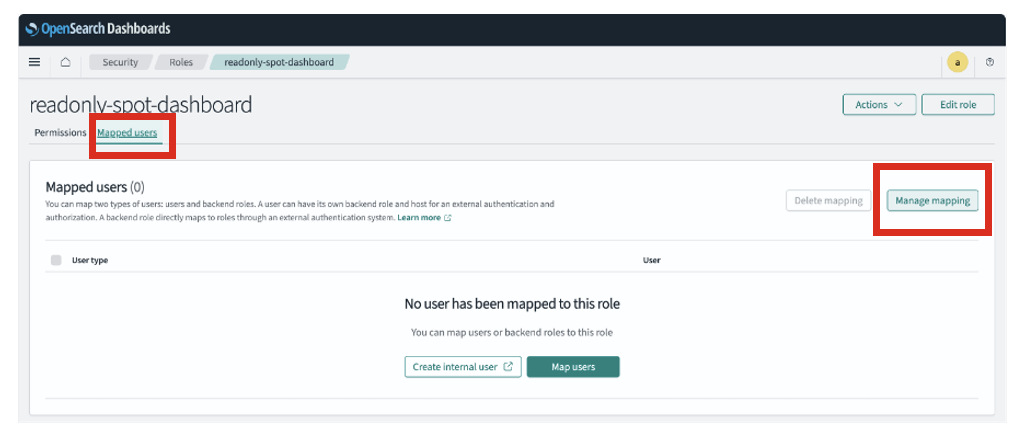
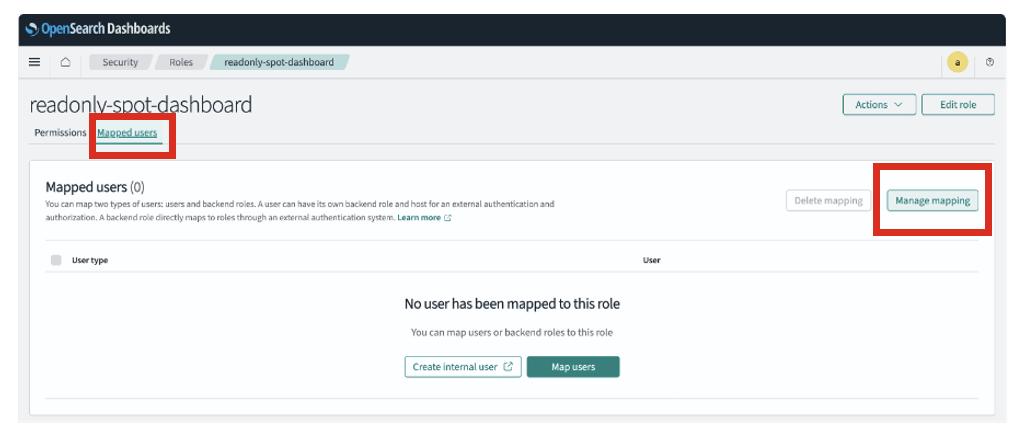
  9. After the role is created, on the same screen, select the ‘Mapped Users’ tab and choose ‘Manage Mapping’

  10. Choose ‘Manage Mapping’
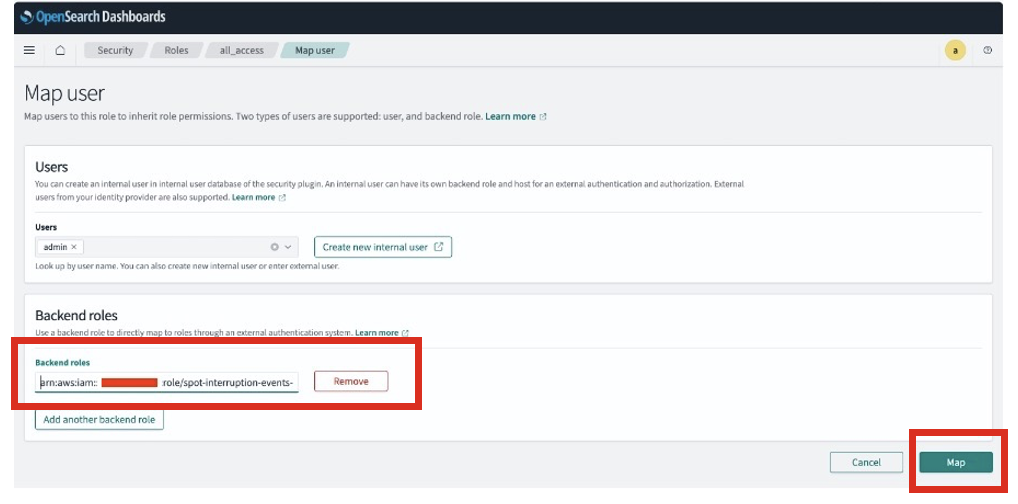
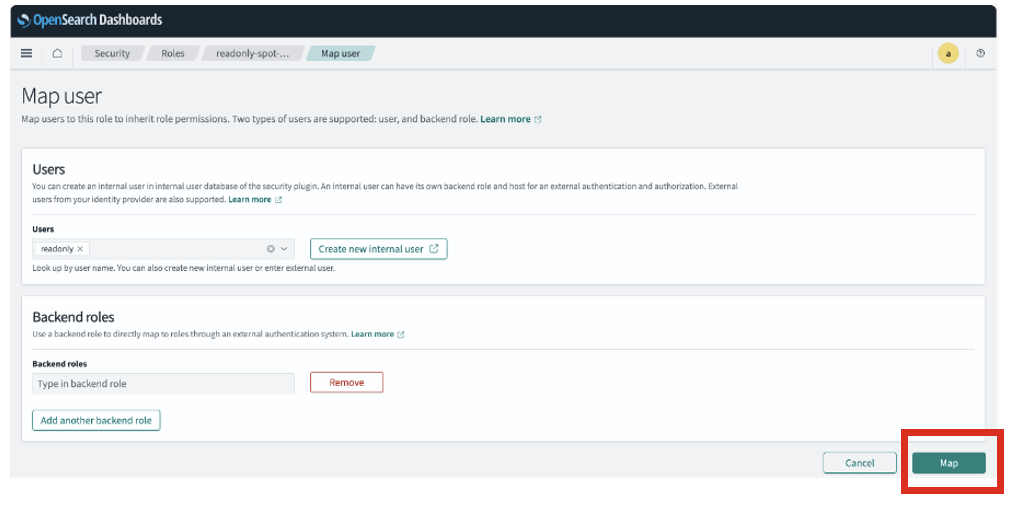
  11. In the ‘Backend roles’ add the Lambda execution role ARN copied earlier and Choose ‘Map’

You can create more users in the internal database and grant appropriate access to the visualisations and dashboards. The following steps show how to create a read only role and to create an internal user and grant read only access.

Manage users and roles

In this section you will create a new user and a role with read-only access, then assign the role to the user to grant them read-only access to the Spot Interruption dashboard and visualizations.

  1. Access the Hamburger Menu icon on the top left
  2. Select ‘Security’ from the bottom of the menu
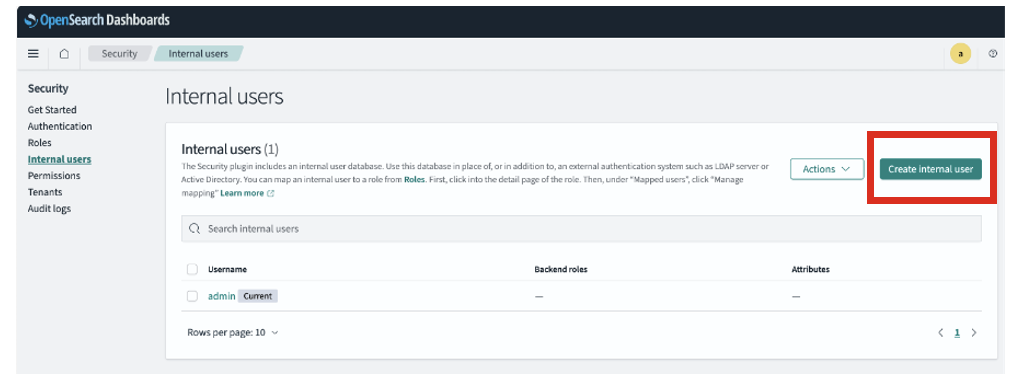
  3. Select ‘Internal Users’ and then select ‘Create Internal user’
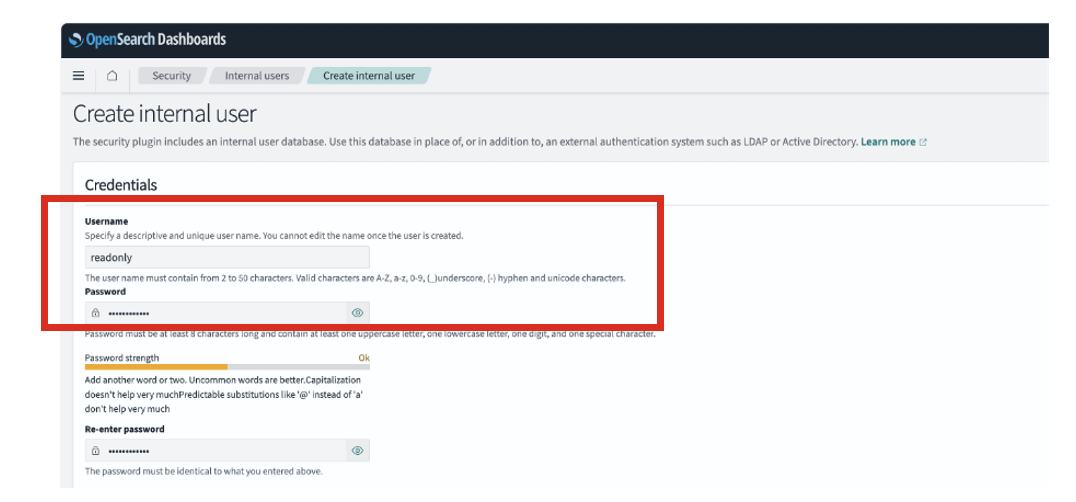
  4. Enter username and set a Password, then choose “Create”.

  5. Now select the ‘Roles’ menu option under ‘Security’ menu and then select ‘Create Role’
    • Enter the role name and set Cluster Permissions to “cluster_composite_ops_ro“.
    • For Index Permissions, select the index pattern name created during deployment.

    See the following screenshot for reference.

  6. Set the Tenant Permissions to “global_tenant” as seen in the image and Choose “Create”.

  7. After the role is created, on the same screen, select the ‘Mapped Users’ tab and choose ‘Manage Mapping’

  8. Select the user created above in ‘Users’ and choose ‘Map’

Configure and deploy sample visualisations and dashboard

Sample visualizations and a starter dashboard are provided under the data folder of the git repo you cloned earlier. Look for the file named spot-interruption-dashboard-visualisations.ndjson.To import the visualizations:

  1. Navigate to Saved Objects under Dashboard Management in OpenSearch Dashboards.
  2. Import the spot-interruption-dashboard-visualisations.ndjson file.
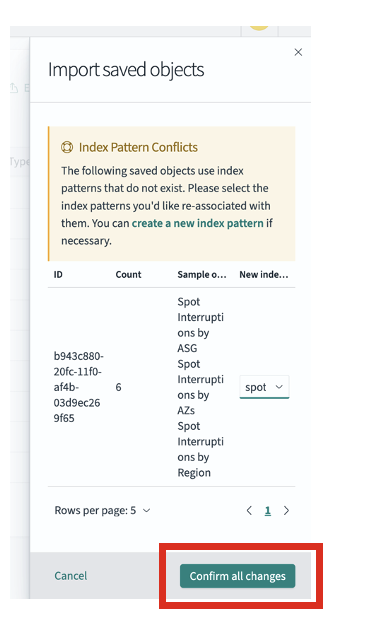
  3. During the import, you may encounter index pattern conflicts. Select the index pattern you created from the dropdown and choose “Confirm all changes”.

Once imported, the sample visualizations and dashboard linked to your index pattern will be available under Dashboards in the left-side hamburger menu. You can view the Spot Interruption Dashboard, which includes visualizations based on Availability Zones, Regions, Instance Types, Auto Scaling Groups (ASGs), and Interruptions over time. You can further customize by creating your own visualizations using the attributes available in the index or by editing/creating new dashboards. The dashboard will display empty views until Spot interruption data is available to visualize.

Test the solution

A temporary event rule was created during deployment to simulate matching Amazon EC2 Spot interruption notices. The rule name is the name you specified during deployment for the CustomEventRuleName parameter.

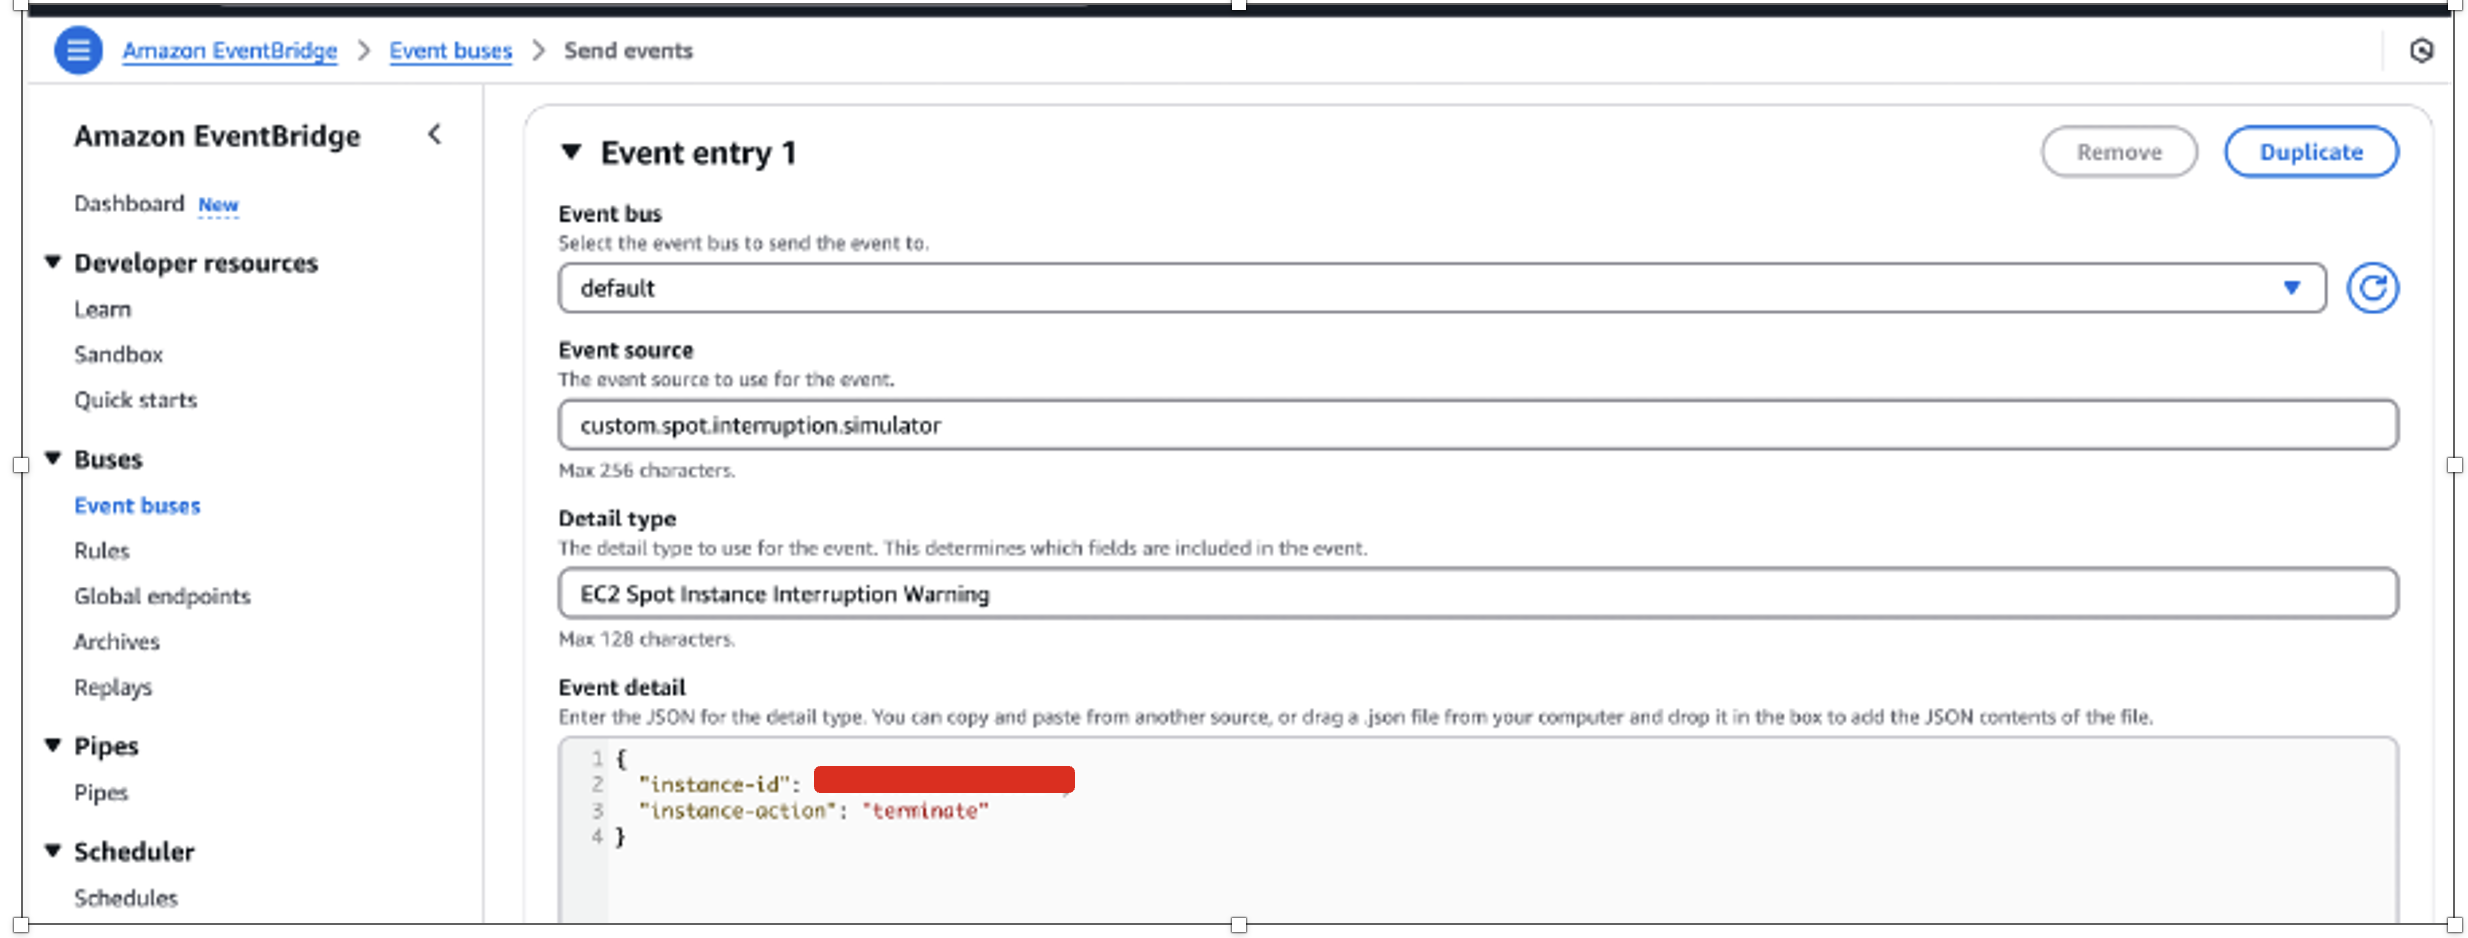
To verify the solution, you can send sample events from the EventBridge console as depicted below. In the AWS console,

  • Open the Amazon EventBridge console
  • In the left menu under ‘Buses’ section choose ‘Event buses’
  • Choose the ‘default’ event bus
  • Choose the ‘Send events’ button
  • In the Send events page enter the following details:
    • Event bus: default
    • Event source: custom.spot.interruption.simulator
    • Detail type: EC2 Spot Instance Interruption Warning
    • Event detail: {"instance-id": "<instance-id>", "Instance-action": "terminate"}

    Replace the instance-id with an actual instance id that is associated with an Amazon EC2 Auto Scaling group. Refer to the following screenshot.

After the event is sent successfully, you can log in to OpenSearch Dashboards and view the Spot Interruption Dashboard, which has been prebuilt with the indexed event data. This dashboard provides insights across key dimensions such as Availability Zones, Regions, instance types, Auto Scaling groups, and interruption trends over time. Use the dashboard as a starting point to understand the kinds of insights possible and customize or create new visualizations based on your needs and the fields available in the index.

Alternatively, you can navigate to the Discover section in the menu to view the raw event details. Ensure that you select the index pattern you created earlier in this demonstration, and adjust the time range if necessary (such as the last 15 minutes) to view the latest data.

Security and cost optimizations

This solution is designed to be secure and cost-efficient by default, but there are some more optimizations you can apply to further reduce cost and enhance security:

Security best practices

  1. Amazon Cognito Authentication : Integrate Amazon Cognito with OpenSearch Dashboards to manage user authentication, enable Multi Factor Authentication, and avoid hardcoding admin credentials. More information Configuring Amazon Cognito authentication for OpenSearch Dashboards
  2. Lambda Layer Versioning: Ensure pinned versions of Lambda Layers are used to avoid unexpected changes. More information Managing Lambda dependencies with layers
  3. Logging and Threat Detection: Enable AWS CloudTrail and Amazon GuardDuty to monitor for unauthorized activity or anomalies. More information Monitoring Amazon OpenSearch Service API calls with AWS CloudTrail

Cost optimizations

  1. Bulk Indexing with Throttling Controls: Lambda processes batches and respects throttling limits to avoid excessive OpenSearch usage.
  2. Short Retention for CloudWatch Logs: Tune log retention periods to avoid unnecessary storage costs.
  3. Optimize Visualizations: Design saved visualizations to avoid expensive queries (like wide time ranges and large aggregations). More information Optimizing query performance for Amazon OpenSearch Service data sources
  4. Index State Management (ISM) : Configure ISM policies in OpenSearch to delete or archive older interruption data. More information Index State Management in Amazon OpenSearch Service

Cleanup

Run the following command to delete the resources deployed earlier.

sam delete

After deleting the stack, make sure to also remove any post-deployment configurations you may have created within the OpenSearch Service dashboards console. While these configurations won’t incur additional costs, it’s considered a best practice to clean up your environment by deleting any resources that are no longer needed. Take some time to review the OpenSearch Service dashboards and identify any custom settings, dashboards, or visualizations you set up during the deployment process. Then, delete these individual configurations to ensure your environment is fully cleaned up.

Conclusion

In this post, you learned how to build and deploy a comprehensive Spot Instance interruption monitoring solution for Auto Scaling groups by using EventBridge, Amazon SQS, Lambda, and OpenSearch Service. You implemented an event-driven pipeline to capture and process Amazon EC2 Spot Instance interruption events, created secure analytics dashboards, and established real-time visibility into interruption patterns across your Auto Scaling group–managed workloads.

This post’s solution empowers your teams with the visibility and agility needed to operate confidently with Amazon EC2 Spot Instances. By combining event-driven architecture with secure, scalable analytics, you can now proactively monitor interruption events, identify interruption trends, and optimize workload strategies for resilience and cost-efficiency.

With real-time data at your fingertips, you’re equipped to make smarter infrastructure decisions and maximize the benefits of Spot Instance capacity while minimizing disruption risks.


About the author

Shekhar Shrinivasan

Shekhar Shrinivasan

Shekhar is a Senior Technical consultant who specializes in cloud architecture design, migration strategies, and AWS workload optimization. He helps enterprise customers accelerate their digital transformation through best practices implementation, scalable infrastructure solutions, and strategic technical guidance to maximize their cloud return on investment.

Optimize efficiency with language analyzers using scalable multilingual search in Amazon OpenSearch Service

Post Syndicated from Sunil Ramachandra original https://aws.amazon.com/blogs/big-data/optimize-efficiency-with-language-analyzers-using-scalable-multilingual-search-in-amazon-opensearch-service/

Organizations manage content across multiple languages as they expand globally. Ecommerce platforms, customer support systems, and knowledge bases require efficient multilingual search capabilities to serve diverse user bases effectively. This unified search approach helps multinational organizations maintain centralized content repositories while making sure users, regardless of their preferred language, can effectively find and access relevant information.

Building multi-language applications using language analyzers with OpenSearch commonly involves a significant challenge: multi-language documents require manual preprocessing. This means that in your application, for every document, you must first identify each field’s language, then categorize and label it, storing content in separate, pre-defined language fields (for example, name_en, name_es, and so on) in order to use language analyzers in search to improve search relevancy. This client-side effort is complex, adding workload for language detection, potentially slowing data ingestion, and risking accuracy issues if languages are misidentified. It’s a labor-intensive approach. However, Amazon OpenSearch Service 2.15+ introduces an AI-based ML inference processor. This new feature automatically identifies and tags document languages during ingestion, streamlining the process and removing the burden from your application.

By harnessing the power of AI and using context-aware data modeling and intelligent analyzer selection, this automated solution streamlines document processing by minimizing manual language tagging, and enables automatic language detection during ingestion, providing organizations sophisticated multilingual search capabilities.

Using language identification in OpenSearch Service offers the following benefits:

  • Enhanced user experience – Users can now find relevant content regardless of the language they search in
  • Increased content discovery – The service can surface valuable content across language silos
  • Improved search accuracy – Language-specific analyzers provide better search relevance
  • Automated processing – You can reduce manual language tagging and classification

In this post, we share how to implement a scalable multilingual search solution using OpenSearch Service.

Solution overview

The solution eliminates manual language preprocessing by automatically detecting and handling multilingual content during document ingestion. Instead of manually creating separate language fields (en_notes, es_notes, and so on) or implementing custom language detection systems, the ML inference processor identifies languages and creates appropriate field mappings.

This automated approach improves accuracy compared to traditional manual methods and reduces development complexity and processing overhead, allowing organizations to focus on delivering better search experiences to their global users.

The solution comprises the following key components:

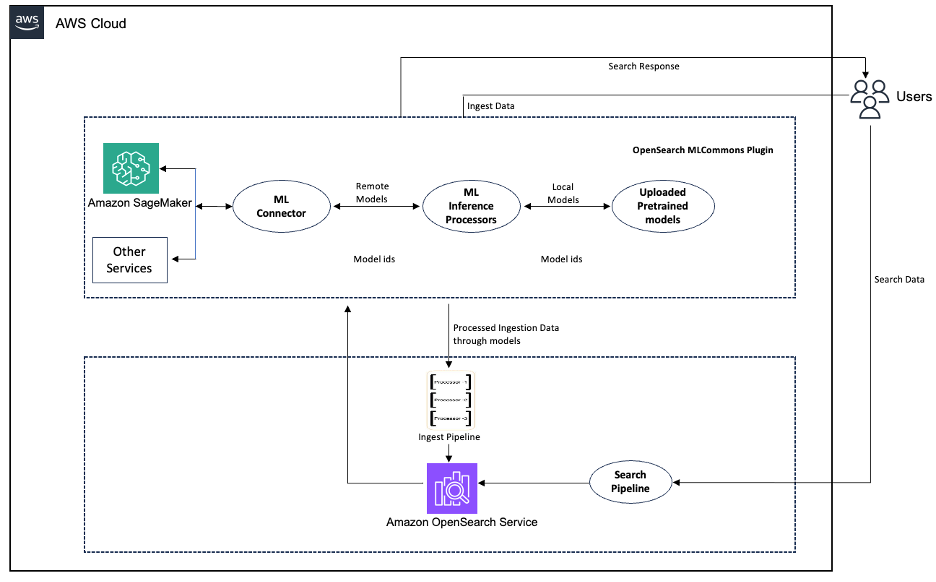
  • ML inference processor – Invokes ML models during document ingestion to enrich content with language metadata
  • Amazon SageMaker integration – Hosts pre-trained language identification models that analyze text fields and return language predictions
  • Language-specific indexing – Applies appropriate analyzers based on detected languages, providing proper handling of stemming, stop words, and character normalization
  • Connector framework – Enables secure communication between OpenSearch Service and Amazon SageMaker endpoints through AWS Identity and Access Management (IAM) role-based authentication.

The following diagram illustrates the workflow of the language detection pipeline.

Workflow of the language detection pipeline

 Figure 1: Workflow of the language detection pipeline

This example demonstrates text classification using XLM-RoBERTa-base for language detection on Amazon SageMaker. You have flexibility in choosing your models and can alternatively use the built-in language detection capabilities of Amazon Comprehend.

In the following sections, we walk through the steps to deploy the solution. For detailed implementation instructions, including code examples and configuration templates, refer to the comprehensive tutorial in the OpenSearch ML Commons GitHub repository.

Prerequisites

You must have the following prerequisites:

Deploy the model

Deploy a pre-trained language identification model on Amazon SageMaker. The XLM-RoBERTa model provides robust multilingual language detection capabilities suitable for most use cases.

Configure the connector

Create an ML connector to establish a secure connection between OpenSearch Service and Amazon SageMaker endpoints, primarily for language detection tasks. The process begins with setting up authentication through IAM roles and policies, applying proper permissions for both services to communicate securely.

After you configure the connector with the appropriate endpoint URLs and credentials, the model is registered and deployed in OpenSearch Service and its modelID is used in subsequent steps.

POST /_plugins/_ml/models/_register
{
  "name": "sagemaker-language-identification",
  "version": "1",
  "function_name": "remote",
  "description": "Remote model for language identification",
  "connector_id": "your_connector_id"
}

Sample response:

{
  "task_id": "hbYheJEBXV92Z6oda7Xb",
  "status": "CREATED",
  "model_id": "hrYheJEBXV92Z6oda7X7"
}

After you configure the connector, you can test is by sending text to the model through OpenSearch Service, and it will return the detected language (for example, sending “Say this is a test” returns en for English).

POST /_plugins/_ml/models/your_model_id/_predict
{
  "parameters": {
    "inputs": "Say this is a test"
  }
}
{
  "inference_results": [
    {
      "output": [
        {
          "name": "response",
          "dataAsMap": {
            "response": [
              {
                "label": "en",
                "score": 0.9411176443099976
              }
            ]
          }
        }
      ]
    }
  ]
}

Set up the ingest pipeline

Configure the ingest pipeline, which uses ML inference processors to automatically detect the language of the content in the name and notes fields of incoming documents. After language detection, the pipeline creates new language-specific fields by copying the original content to new fields with language suffixes (for example, name_en for English content).

The pipeline uses an ml_inference processor to perform the language detection and copy processors to create the new language-specific fields, making it straightforward to handle multilingual content in your OpenSearch Service index.

PUT _ingest/pipeline/language_classification_pipeline{
  "description": "ingest task details and classify languages",
  "processors": [
    {
      "ml_inference": {
        "": "6s71PJQBPmWsJ5TTUQmc",
        "input_map": [
          {
            "inputs": "name"
          },
          {
            "inputs": "notes"
          }
        ],
        "output_map": [
          {
            "predicted_name_language": "response[0].label"
          },
          {
            "predicted_notes_language": "response[0].label"
          }
        ]
      }
    },
    {
      "copy": {
        "source_field": "name",
        "target_field": "name_{{predicted_name_language}}",
        "ignore_missing": true,
        "override_target": false,
        "remove_source": false
      }
    }
  ]
}
{
  "acknowledged": true
}

Configure the index and ingest documents

Create an index with the ingest pipeline that automatically detects the language of incoming documents and applies appropriate language-specific analysis. When documents are ingested, the system identifies the language of key fields, creates language-specific versions of those fields, and indexes them using the correct language analyzer. This allows for efficient and accurate searching across documents in multiple languages without requiring manual language specification for each document.

Here’s a sample index creation API call demonstrating different language mappings.

PUT /task_index
{
  "settings": {
    "index": {
      "default_pipeline": "language_classification_pipeline"
    }
  },
  "mappings": {
    "properties": {
      "name_en": { "type": "text", "analyzer": "english" },
      "name_es": { "type": "text", "analyzer": "spanish" },
      "name_de": { "type": "text", "analyzer": "german" },
      "notes_en": { "type": "text", "analyzer": "english" },
      "notes_es": { "type": "text", "analyzer": "spanish" },
      "notes_de": { "type": "text", "analyzer": "german" }
    }
  }
}

Next, ingest this input document in German

{
  "name": "Kaufen Sie Katzenminze",
  "notes": "Mittens mag die Sachen von Humboldt wirklich."
}

The German text used in the preceding code will be processed using a German-specific analyzer, supporting proper handling of language-specific characteristics such as compound words and special characters.

After successful ingestion into OpenSearch Service, the resulting document appears as follows:

{
  "_source": {
    "predicted_notes_language": "en",
    "name_en": "Buy catnip",
    "notes": "Mittens really likes the stuff from Humboldt.",
    "predicted_name_language": "en",
    "name": "Buy catnip",
    "notes_en": "Mittens really likes the stuff from Humboldt."
  }
}

Search documents

This step demonstrates the search capability after the multilingual setup. By using a multi_match query with name_* fields, it searches across all language-specific name fields (name_en, name_es, name_de) and successfully finds the Spanish document when searching for “comprar” because the content was properly analyzed using the Spanish analyzer. This example shows how the language-specific indexing enables accurate search results in the correct language without needing to specify which language you’re searching in.

GET /task_index/_search
{
  "query": {
    "multi_match": {
      "query": "comprar",
      "fields": ["name_*"]
    }
  }
}

This search correctly finds the Spanish document because the name_es field is analyzed using the Spanish analyzer:

{
  "hits": {
    "total": { "value": 1, "relation": "eq" },
    "max_score": 0.9331132,
    "hits": [
      {
        "_index": "task_index",
        "_id": "3",
        "_score": 0.9331132,
        "_source": {
          "name_es": "comprar hierba gatera",
          "notes": "A Mittens le gustan mucho las cosas de Humboldt.",
          "predicted_notes_language": "es",
          "predicted_name_language": "es",
          "name": "comprar hierba gatera",
          "notes_es": "A Mittens le gustan mucho las cosas de Humboldt."
        }
      }
    ]
  }
}

Cleanup

To avoid ongoing charges and delete the resources created in this tutorial, perform the following cleanup steps

  1. Delete the Opensearch service domain. This stops both storage costs for your vectorized data and any associated compute charges.
  2. Delete the ML connector that links your OpenSearch service to your machine learning model.
  3. Finally, delete your Amazon SageMaker endpoints and resources.

Conclusion

Implementing multilingual search with OpenSearch Service can help organizations break down language barriers and unlock the full value of their global content. The ML inference processor provides a scalable, automated approach to language detection that improves search accuracy and user experience.

This solution addresses the growing need for multilingual content management as organizations expand globally. By automatically detecting document languages and applying appropriate linguistic processing, businesses can deliver comprehensive search experiences that serve diverse user bases effectively.


About the authors

Sunil Ramachandra

Sunil Ramachandra

Sunil is a Senior Solutions Architect at AWS, enabling hyper-growth Independent Software Vendors (ISVs) to innovate and accelerate on AWS. He partners with customers to build highly scalable and resilient cloud architectures. When not collaborating with customers, Sunil enjoys spending time with family, running, meditating, and watching movies on Prime Video.

Mingshi Liu

Mingshi Liu

Mingshi is a Machine Learning Engineer at AWS, primarily contributing to OpenSearch, ML Commons and Search Processors repo. Her work focuses on developing and integrating machine learning features for search technologies and other open-source projects.

Sampath Kathirvel

Sampath Kathirvel

Sampath is a Senior Solutions Architect at AWS who guides leading ISV organizations in their cloud transformation journey. His expertise lies in crafting robust architectural frameworks and delivering strategic technical guidance to help businesses thrive in the digital landscape. With a passion for technology innovation, Sampath empowers customers to leverage AWS services effectively for their mission-critical workloads.

Search++, Going Beyond Keywords with Amazon OpenSearch Service

Post Syndicated from Prashant Agrawal original https://aws.amazon.com/blogs/big-data/search-going-beyond-keywords-with-amazon-opensearch-service/

Search technology, specifically web search technology, has been around for more than 30 years. You entered a few words in a text box, clicked “Search,” and received a series of links. However, the results were often a mix of related, non-related, and general links. If the results didn’t contain the information you needed, you reformulated your query and submitted it to the search engine again. Some of the breakdowns occurred around language—the text you matched was missing some context that disambiguated your search terms. Other breakdowns were conceptual in nature—you made inferences yourself that led you to new, successful search terms. In all cases, you were the agent that adjusted your search until you received the right information in response. Search engines fail to understand context, so you had to act as translators between your information needs and the rigid keyword system.

With the advent of natural language models like large language models (LLMs) and foundation models (FMs), AI-powered search systems are able to incorporate more of the searcher’s intelligence into the application, relieving you of some of the burden of iterating over search results. On the search side, application designers can choose to employ semantic, hybrid, multimodal, and sparse search. These methods use LLMs and other models to generate a vector representation of a piece of text and a query to provide nearest-neighbor matching. On the application side, application designers are employing AI agents embedded in workflows that can make multiple passes over the search system, rewrite user queries, and rescore results. With these advances, searchers expect intelligent, context-aware results.

As user interactions become more nuanced, many organizations are enhancing their existing search capabilities with intent-based understanding. The emergence of language models that create vector embeddings brings opportunities to further enhance search systems by combining traditional relevancy algorithms with semantic understanding. This hybrid approach allows applications to better interpret user intent, handle natural language variations, and deliver more contextually relevant results. By integrating these complementary capabilities, organizations can build upon their robust search infrastructure to create more intuitive and responsive search experiences that understand the keywords and also the reason behind the query.

This post describes how organizations can enhance their existing search capabilities with vector embeddings using Amazon OpenSearch Service. We discuss why traditional keyword search falls short of modern user expectations, how vector search enables more intelligent and contextual results, and the measurable business impact achieved by organizations like Amazon Prime Video, Juicebox, and Amazon Music. We examine the practical steps for modernizing search infrastructure while maintaining the precision of traditional search systems. This post is the first in a series designed to guide you through implementing modernized search applications, using technologies such as vector search, generative AI, and agentic AI to create more powerful and intuitive search experiences.

Going beyond keyword search

Keyword-based search engines remain essential in today’s digital landscape, providing precise results for product matching and structured queries. Although these traditional systems excel at exact matches and metadata filtering, many organizations are enhancing them with semantic capabilities to better understand user intent and natural language variations. This complementary approach allows search systems to maintain their foundational strengths while adapting to more diverse search patterns and user expectations. In practice, this leads to several business-critical challenges:

  • Missed opportunities and inefficient discovery – Traditional search approaches tend to oversimplify user intent, grouping diverse search behaviors into broad categories. When Amazon Prime Video users searched for “live soccer,” the search results included documentaries like “This is Football: Season 1”; users were seeing irrelevant results that were keyword matches, but missed the context encoded in “live” as a keyword.
  • Inability to adapt to changing search behavior – Search behavior is evolving rapidly. Users now employ conversational language, ask full questions, and expect systems to understand context and nuance. Juicebox encountered this challenge with recruiting search engines that relied on simple Boolean or keyword-based searches, and couldn’t capture the nuance and intent behind complex recruiting queries, leading to large volumes of irrelevant results.
  • Limited personalization and contextual understanding – Search engines can be enhanced with personalization capabilities through additional investment in technology and infrastructure. For example, Amazon Music improved its recommendation system by augmenting traditional search capabilities with personalization features, allowing the service to consider user preferences, listening history, and behavioral patterns when delivering results. This demonstrates how organizations can build upon fundamental search functionality to create more tailored experiences when specific use cases warrant the investment.
  • Hidden business impact of poor search – Inefficient search also has measurable business impacts. For instance, Juicebox recruiters were spending unnecessary time filtering through irrelevant results, making the process time-consuming and inefficient. Amazon Prime Video discovered that their original search experience, designed for movies and TV shows, wasn’t meeting the needs of sports fans, creating a disconnect between search queries and relevant results.

Importance of building modern search applications

Organizations are at a pivotal moment in enterprise search evolution. User interactions with information are fundamentally changing and analysts predict that the shift from traditional search interactions to AI-powered interfaces will continue to accelerate through 2026, as users increasingly expect more conversational and context-aware experiences. This transformation reflects evolving user expectations for more intuitive, intent-driven search experiences that understand not just what users type, but what they mean.

Real-world implementations demonstrate the tangible value of enhancing existing search. Examples like Amazon Prime Video and Juicebox demonstrate how semantic understanding and augmenting traditional search with vector capabilities can improve performance and increase end-customer satisfaction. The ability to deliver personalized, context-aware search experiences is becoming a key differentiator in today’s digital landscape.

Although organizations recognize these opportunities, many seek guidance on practical implementation. Successful organizations are taking a complementary approach by enhancing their proven search infrastructure with vector capabilities rather than replacing existing systems. Organizations can deliver more sophisticated search experiences that meet both current and future user needs, combining traditional search precision with semantic understand. The path forward isn’t about replacing existing search systems but enhancing them to create more powerful, intuitive search experiences that drive measurable business value.

Transforming business value and user experiences with vector search

Building upon the strong foundation of traditional search systems, businesses are expanding their search functionality to support more conversational interactions and diverse content types. Vector search complements existing search capabilities, helping organizations extend their search experiences into new domains while maintaining the precision and reliability that traditional search provides. This combination of proven search technology with emerging capabilities creates opportunities for more dynamic and interactive user experiences.

If you’re using OpenSearch Service to power your keyword search, you’re already using a scalable, reliable solution. Juicebox’s migration to vector search reduced query latency from 700 milliseconds to 250 milliseconds while surfacing 35% more relevant candidates for complex queries. Despite handling a massive database of 800 million profiles, the system maintained high recall accuracy and delivered aggregation queries across 100 million profiles. Amazon Music’s success story further reinforces the scalability of vector search solutions. Their recommendation system now efficiently manages 1.05 billion vectors, handling peak loads of 7,100 vector queries per second across multiple geographies to power real-time music recommendations for their vast catalog of 100 million songs.

How vector embeddings transform user experience

Consumers increasingly rely on digital platforms and apps to quickly discover healthy and delicious meal options, especially as busy schedules leave little time for meal planning and preparation. For organizations building these applications, the traditional keyword-based search approach often falls short in delivering the most relevant results to their users. This is where vector search, powered by embeddings and semantic understanding, can make a significant difference.

Imagine you’re a developer at an ecommerce company building a food delivery app for your customers. When a user enters a search query like “Quick, healthy dinner with tofu, no dairy,” a traditional keyword-based search would only return recipes that explicitly contain those exact words in the metadata. This approach has several shortcomings:

  • Missed synonyms – Recipes labeled as “30-minute meals” instead of “quick” would be missed, even though they match the user’s intent.
  • Lack of semantic understanding – Dishes that are healthy and nutrient-dense, but don’t use the word “healthy” in the metadata, would not be surfaced. The search engine lacks the ability to understand the semantic relationship between “healthy” and nutritional value.
  • Inability to detect absence of ingredients – Recipes that don’t contain dairy but don’t explicitly state “dairy-free” would also be missed. The search engine can’t infer the absence of an ingredient.

This limitation means organizations miss valuable opportunities to delight their users and keep them engaged. Imagine if your app’s search function could truly understand the user’s intent, by correlating that “quick” refers to meals under 30 minutes, “healthy” relates to nutrient density, and “no dairy” means excluding ingredients like milk, butter, or cheese. This is precisely where vector search powered by embeddings and semantic understanding can transform the user experience.

Conclusion

This post covered key concepts and business benefits of incorporating vector search into your existing applications and infrastructure. We discussed the limitations of traditional keyword-based search and how vector search can significantly improve user experience. Vector search, powered by generative AI, can detect relevant attributes, better infer the presence or absence of specific criteria, and surface results that better align with user intent, whether your users are searching for products, recipes, research, or knowledge.

Modernizing your search capabilities with vector embeddings is a strategic move that can drive engagement, improve satisfaction, and deliver measurable business outcomes. By taking incremental steps to integrate vector search, your organization can future-proof its applications and stay ahead in an ever-evolving digital landscape.

Our next post will dive into Automatic Semantic Enrichment. We discuss how to generate semantic embeddings using Amazon Bedrock, set up vector-based indexes in OpenSearch Service, and combine vector and keyword search for even more relevant results. We provide step-by-step guidance and sample code to help you enhance your OpenSearch Service infrastructure with vector search, so your users can discover and engage with your data in more meaningful ways.

To learn more, refer to Amazon OpenSearch Service as a Vector Database, and visit our Migration Hub if you’re looking for migration and system modernization guidance and resources. For more blog posts about vector databases, refer to the AWS Big Data Blog. The following posts can help you learn more about vector database best practices and OpenSearch Service capabilities:

Scaling cluster manager and admin APIs in Amazon OpenSearch Service

Post Syndicated from Rajiv Kumar Vaidyanathan original https://aws.amazon.com/blogs/big-data/scaling-cluster-manager-and-admin-apis-in-amazon-opensearch-service/

Amazon OpenSearch Service is a managed service that makes it simple to deploy, secure, and operate OpenSearch clusters at scale in the AWS Cloud. A typical OpenSearch cluster is comprised of cluster manager, data, and coordinator nodes. It is recommended to have three cluster manager nodes, and one of them will be elected as a leader node.

Amazon OpenSearch Service introduced support for 1,000-node OpenSearch Service clusters capable of handling 500,000 shards with OpenSearch Service version 2.17. For large clusters, we have identified bottlenecks in admin API interactions (with the leader) and introduced improvements in OpenSearch Service version 2.17. These improvements have helped OpenSearch Service to publish cluster metrics and monitor at same frequency for large clusters while maintaining the optimal resource usage (less than 10% CPU and less than 75% JVM usage) on the leader node (16 core CPU with 64 GB JVM heap). It has also ensured that metadata management can be performed on large clusters with predictable latency without destabilizing the leader node.

General monitoring of an OpenSearch node using health check and statistics API endpoints doesn’t cause visible load to the leader. But as the number of nodes increase in the cluster, the volume of these monitoring calls also increases proportionally. The increase in the call volume coupled with the less optimal implementation of these endpoints overwhelms the leader node, resulting in stability issues. In this post, we demonstrate the different bottlenecks that were identified and the corresponding solutions that were implemented in OpenSearch Service to scale cluster manager for large cluster deployments. These optimizations are available to all new domains or existing domains upgraded to OpenSearch Service versions 2.17 or above.

Cluster state

To understand the various bottlenecks with the cluster manager, let’s examine the cluster state, whose management is the core operation of the leader. The cluster state contains the following key metadata information:

  • Cluster settings
  • Index metadata, which includes index settings, mappings, and alias
  • Routing table and shard metadata, which contains details of shard allocation to nodes
  • Node information and attributes
  • Snapshot information, custom metadata, and so on

Node, index, and shard are managed as first-class entities by the cluster manager and contain information such as identifier, name, and attributes for each of their instances.

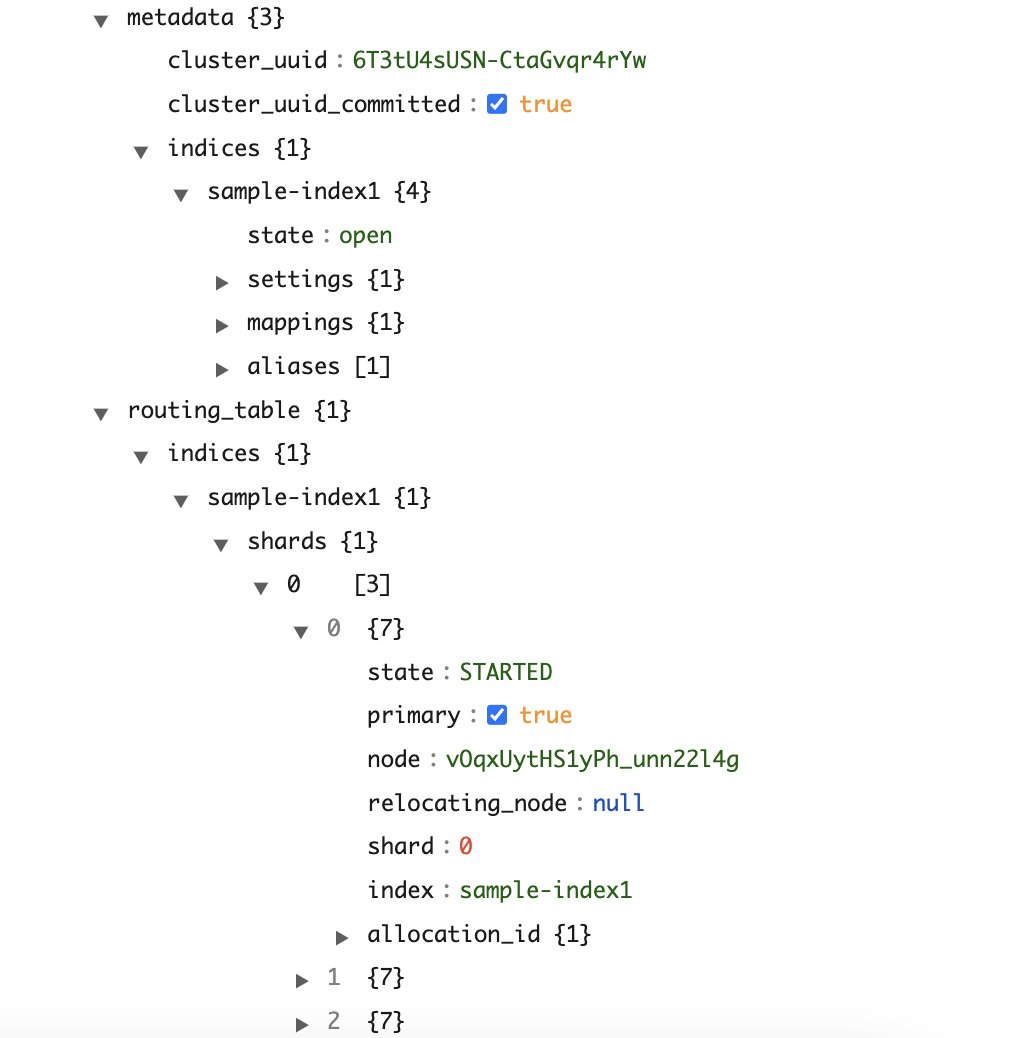
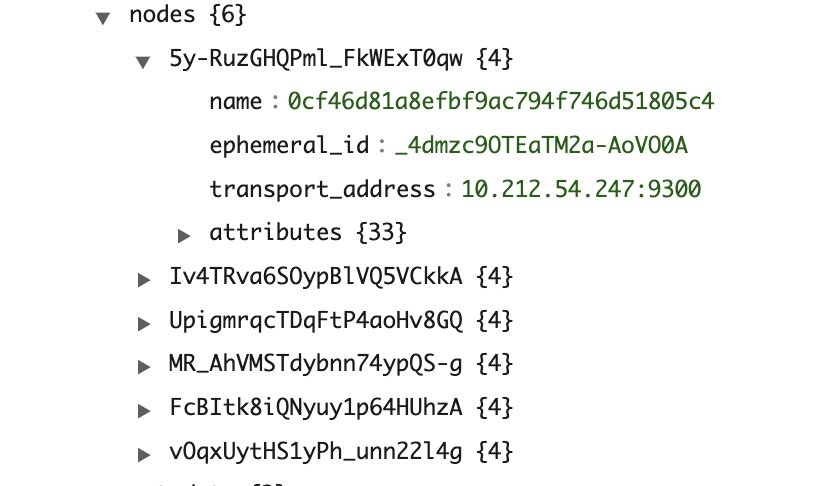
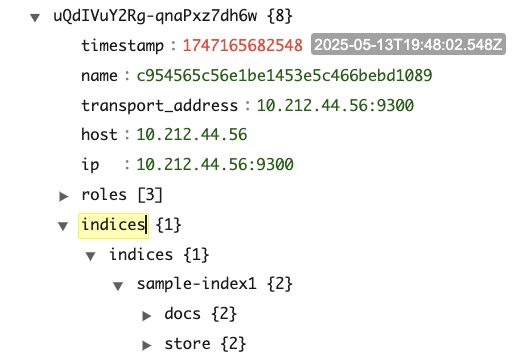
The following screenshots are from a sample cluster state for a cluster with three cluster manager and three data nodes. The cluster has a single index (sample-index1) with one primary and two replicas.

Cluster metadata showing index and shard configuration

Nodes metadata

As shown in the screenshots, the number of entries in the cluster state is as follows:

  • IndexMetadata (metadata#indices) has entries equal to the total number of indexes
  • RoutingTable (routing_table) has entries equal to the number of indexes multiplied by the number of shards per index
  • NodeInfo (nodes) has entries equal to the number of nodes in the cluster

The size of a sample cluster state with six nodes, one index, and three shards is around 15 KB (size of JSON response from the API). Consider a cluster with 1,000 nodes, which has 10,000 indexes with an average of 50 shards per index. The cluster state would have 10,000 entries for IndexMetadata, 500,000 entries for RoutingTable, and 1,000 entries for NodeInfo.

Bottleneck 1: Cluster state communication

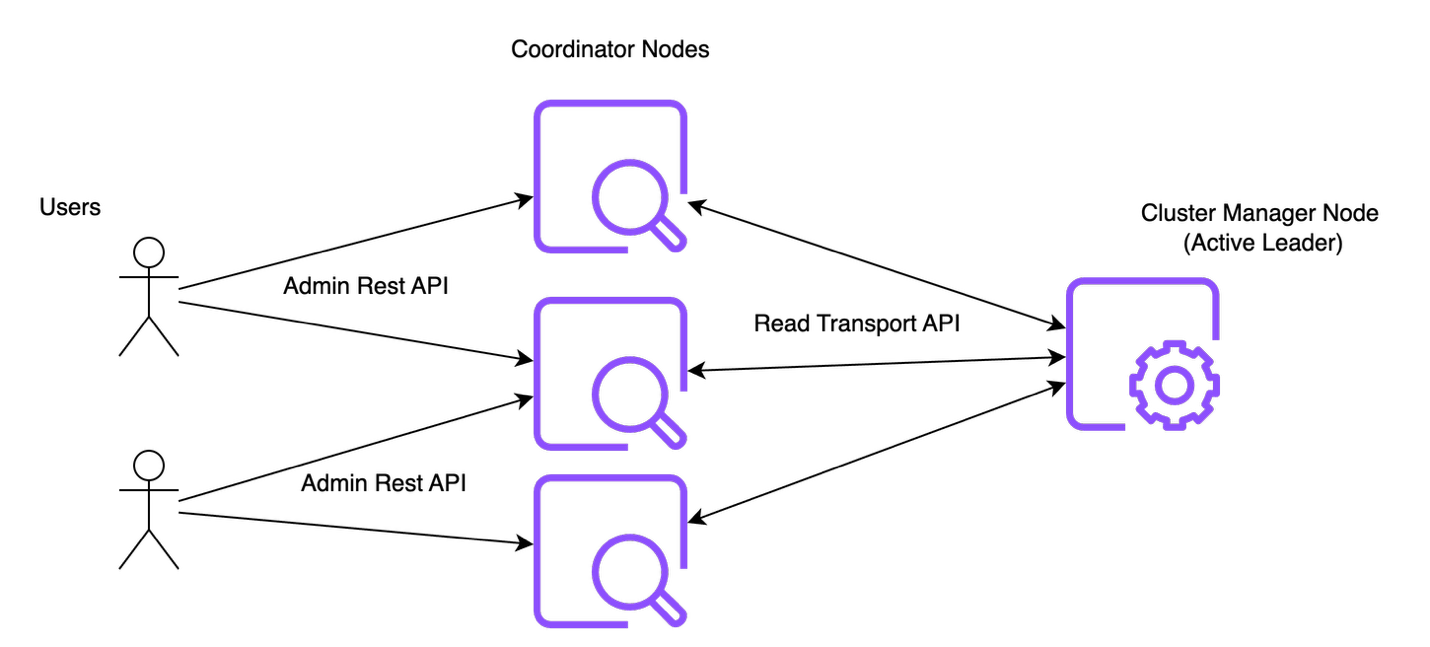
OpenSearch provides admin APIs as a REST endpoint for users to manage and configure the cluster metadata. Admin API requests are handled by either coordinator node (or) by data node if the cluster does not have dedicated coordinator node provisioned. You can use admin APIs to check cluster health, modify settings, retrieve statistics, and more. Some of the examples are the CAT, Cluster Settings, and Node Stats APIs.

The following diagram illustrates the admin API control flow.

Admin API Request Flow

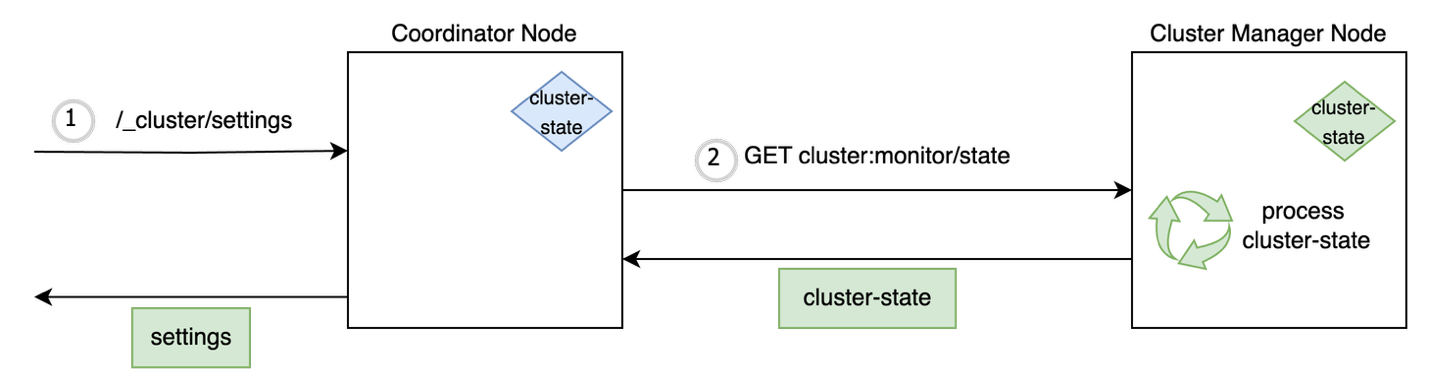
Let’s consider a Read API request to fetch information about the cluster settings.

  1. The user makes the call to the HTTP endpoint backed by the coordinator node.
  2. The coordinator node initiates an internal transport call to the leader of the cluster.
  3. The transport handler in the leader node performs a filter and selection of metadata based on the input request from the latest cluster state.
  4. The processed cluster state is then returned back to the coordinating node, which then generates the response and finishes the request processing.

The cluster state processing on the nodes is shown in the following diagram.

Request Processing using Cluster State

As discussed earlier, most of the admin read requests require the latest cluster state and the node which processes the API request and makes a _cluster/state call to the leader. In a cluster setup of 1,000 nodes and 500,000 shards, the size of the cluster state would be around 250 MB. This can overload leader and cause the following issues:

  • CPU usage increases on the leader due to simultaneous admin calls because the leader has to vend the latest state to many coordinating nodes in the cluster simultaneously.
  • The heap memory consumption of the cluster state can grow to multiples of 100 MB depending upon the number of index mappings and settings configured by the user. It causes JVM memory pressure to build on the leader, causing frequent garbage collection pauses.
  • Repeated serialization and transfer of the large cluster state causes transport worker threads to be busy on the leader node, potentially causing delays and timeouts of further requests.

The leader node sends periodic ping requests to follower nodes and requires transport threads to process the responses. Because the number of threads serving the transport channel is limited (defaults to the number of processor cores), the responses are not processed in a timely fashion. The leader-follower health checks in the cluster get timed out, thereby causing a spiral effect of nodes leaving the cluster and more shard recoveries being initiated by the leader.

Solution: Latest local cluster state

Cluster state is versioned using two long fields: term and version. The term number is incremented whenever a new leader is elected, and the version number is incremented with every metadata update. Given that the latest cluster state is cached on all the nodes, it can be used to serve the admin API request if it is up-to-date with the leader. To check the freshness of the cached copy, a light-weight transport API is introduced, which fetches only the term and version corresponding to the latest cluster state from leader. The request-coordinating node matches it with the local term and version, and if they’re the same, it uses the local cluster sate to serve the admin API read request. If the cached cluster state is out of sync, the node makes a subsequent transport call to fetch the latest cluster state and then serves the incoming API request. This offloads the responsibility of serving read requests to the coordinating node, thereby reducing the load on the leader node.

Cluster state processing on the nodes after the optimization is shown in the following diagram.

Optimized Request Processing

Term-version checks for cluster state processing are now used by 17 read APIs across the _cat and _cluster APIs in OpenSearch.

Impact: Less CPU resource usage on leader

From our load tests, we observed at least 50% reduction in CPU usage without a change in the API latency due to the aforementioned improvement. The load test was performed on an OpenSearch cluster consisting of 3 cluster manager nodes (8 cores each), 5 data nodes (64 cores each), and 25,000 shards with a cluster state size of around 50 MB. The workload consists of the following admin APIs invoked, with periodicity mentioned in the following table:

  • /_cluster/state
  • /_cat/indices
  • /_cat/shards
  • /_cat/allocation
Request Count / 5 minutes CPU (max)
Existing Setup With Optimization
3000 14% 7%
6000 20% 10%
9000 28% 12%

Bottleneck 2: Scatter-gather nature of statistics admin APIs

The next group of admin APIs are used to fetch the statistics information of the cluster. These APIs include _cat/indices, _cat/shards, _cat/segments, _cat/nodes, _cluster/stats, and _nodes/stats, to name a few. Unlike metadata, which is managed by the leader, the statistics information is distributed across the data nodes in the cluster.

For example, consider the response to the _cat/indices API for the index sample-index1:

[
  {
    "health": "green",
    "status": "open",
    "index": "sample-index1",
    "uuid": "QrWpe7aDTRGklmSp5joKyg",
    "pri": "1",
    "rep": "2",
    "docs.count": "30",
    "docs.deleted": "0",
    "store.size": "624b",
    "pri.store.size": "208b"
  }
]

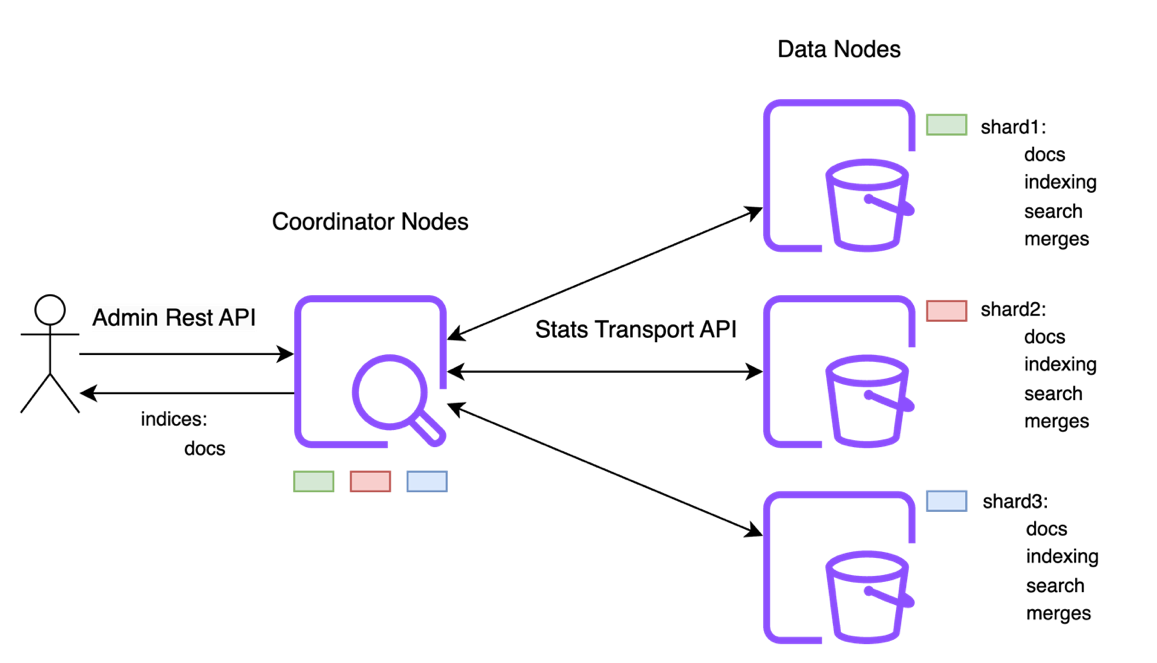
The values for fields docs.count, docs.deleted , store.size, and pri.store.size are fetched from the data nodes, which have the corresponding shards, and are then aggregated by the coordinating node. To compute the preceding response for sample-index1, the coordinator node collects the statistics responses from three data nodes hosting one primary and two replica shards, respectively.

Every data node in the cluster collects statistics related to operations such as indexing, search, merges, and flushes for the shards it manages. Every shard in the cluster has about 150 indices metrics tracked across 20 metric groups.

The response from the data node to coordinator contains all the shard statistics of the index and not just the ones (docs and store stats) requested by the user. The response size of stats returned from data node for a single shard is around 4 KB. The following diagram illustrates the stats data flow among nodes in a cluster.

Stats API Request Flow

For a cluster with 500,000 shards, the coordinator node needs to retrieve stats responses from different nodes whose sizes sum to around 2.5 GB. The retrieval of such large response sizes can cause the following issues:

  • High network throughput volume between nodes.
  • Increased memory pressure because statistics responses returned by data nodes are accumulated in memory of the coordinator node before constructing the user-facing response.

The memory pressure can cause a circuit breaker of the coordinator node to trip, resulting in 429 TOO MANY REQUEST responses. It also results in an increase in CPU utilization on the coordinator node due to garbage collection cycles being triggered to reclaim the heap used for stats requests. The overloading of the coordinator node to fetch statistics information for admin requests can potentially result in rejecting critical API requests such as health check, search, and indexing, resulting in a spiral effect of failures.

Solution: Local aggregation and filtering

Because the admin API returns only the user-requested stats in the response, it is not required by data nodes to send the entire shard-level stats because it’s not requested by the user. We have now introduced stats aggregation at transport action so each data node aggregates the stats locally and then responds back to the coordinator node. Additionally, data nodes support filtering of statistics so only specific shard stats, as requested by the user, can be returned to the coordinator. This results in reduced compute and memory on coordinator nodes because they now work with responses that are far smaller.

The following output is the shard stats returned by a data node to the coordinator node after local aggregation by index. The response is also filtered based on user-requested statistics. The response contains only docs and store metrics aggregated by index for shards present on the node.

Stats Received on Coordinator after Optimization

Impact: Faster response time

The following table shows the latency for health and stats API endpoints in a large cluster. These results are for a cluster size of 3 cluster manager nodes, 1,000 data nodes, and 500,000 shards. As explained in the following pull request, the optimization to pre-compute statistics prior to sending response helps reduce response size and improve latency.

API Response Latency
Existing Setup With Optimization
_cluster/stats 15s 0.65s
_nodes/stats 13.74s 1.69s
_cluster/health 0.56s 0.15s

Bottleneck 3: Long-running stats request

With admin APIs, users can specify the timeout parameter as part of the request. This helps the client fail fast if requests are taking more time to be processed due to an overloaded leader or data node. However, the coordinator node continues to process the request and initiate internal transport requests to data nodes even after the user’s request gets disconnected. This is wasteful work and causes unnecessary load on the cluster because the response from the data node is discarded by the coordinator after the request has timed out. No mechanism exists for the coordinator to track that the request has been cancelled by the user and further downstream transport calls don’t need to be attempted.

Solution: Cancellation at transport layer

To prevent long-running transport requests for admin APIs and reduce the overhead on the already overwhelmed data nodes, cancellation has been implemented at the transport layer. This is now used by the coordinator to cancel the transport requests to data nodes after the user-specified timeout expires.

Impact: Fail fast without cascading failures

The _cat/shards API fails gracefully if the leader is overloaded in case of large clusters. The API returns a timeout response to the user without issuing broadcast calls to data nodes.

Bottleneck 4: Huge response size

Let’s now look at challenges with the popular _cat APIs. Historically, CAT APIs didn’t support pagination because the metadata wasn’t expected to grow to tens of thousands in size when it was designed. This assumption no longer holds for large clusters and can cause compute and memory spikes while serving these APIs.

Solution: Paginated APIs

After careful deliberations with the community, we introduced a new set of paginated list APIs for metadata retrieval. The APIs _list/indices and _list/shards are pagination counterparts to _cat/indices and _cat/shards. The _list APIs maintain pagination stability, so that a paginated dataset maintains order and consistency even when a new index is added or an existing index is removed. This is achieved by using a combination of index creation timestamps and index names as page tokens.

Impact: Bounded response time

_list/shards can now successfully return paginated responses for a cluster with 500,000 shards without getting timed out. Fixed response sizes facilitate faster data retrieval without overwhelming the cluster for large datasets.

Conclusion

Admin API’s are critical for observability and metadata management of OpenSearch domains. Admin APIs, if not designed properly, introduce bottlenecks in the system and impacts the performance of OpenSearch domains. The improvements made for these APIs in version 2.17 have performance gains for all customers of OpenSearch service irrespective of whether it is large-sized (1,000 nodes), mid-sized (200 nodes), or small-sized (20 nodes). It ensures that elected cluster manager node is stable even when the API’s are exercised for domains with large metadata size. OpenSearch is an open source, community-driven software. The foundational pieces of APIs such as pagination, cancellation, and local aggregation are extensible and can be used for other APIs.

If you would like to contribute to OpenSearch, open up a GitHub issue and let us know your thoughts. You could get started with these open PR’s in Github [PR1] [PR2] [PR3] [PR4].


About the authors

Rajiv Kumar

Rajiv Kumar

Rajiv is a Senior Software Engineer working on OpenSearch at Amazon Web Services. He is interested in solving distributed system problems and an active contributor to OpenSearch.

Shweta Thareja

Shweta Thareja

Shweta is a Principal Engineer working on Amazon OpenSearch Service. She is interested in building distributed and autonomous systems. She is a maintainer and an active contributor to OpenSearch.

Amazon OpenSearch Serverless monitoring: A CloudWatch setup guide

Post Syndicated from Urmila Iyer original https://aws.amazon.com/blogs/big-data/amazon-opensearch-serverless-monitoring-a-cloudwatch-setup-guide/

Amazon OpenSearch Serverless simplifies the deployment and management of OpenSearch workloads by automatically scaling based on your usage patterns. The service considers key metrics such as shard utilization, storage consumption, and CPU usage while maintaining millisecond-level response times, with the simplicity of a serverless environment.

While OpenSearch Serverless handles scaling automatically, implementing robust monitoring remains crucial for understanding usage patterns, optimizing costs, helping to ensure performance, and maintaining reliability. Proactive monitoring helps organizations detect critical issues with the applications or infrastructure in real time and identify root causes quickly.

This post is part of our Amazon OpenSearch service monitoring series, focusing on OpenSearch Serverless workloads and deployments. In this post, we explore commonly used Amazon CloudWatch metrics and alarms for OpenSearch Serverless, walking through the process of selecting relevant metrics, setting appropriate thresholds, and configuring alerts. This guide will provide you with a comprehensive monitoring strategy that complements the serverless nature of your OpenSearch deployment while maintaining full operational visibility.

Key benefits of CloudWatch monitoring for OpenSearch Serverless

Implementing CloudWatch monitoring for your OpenSearch Serverless collections offers several key advantages:

  • Near real-time performance monitoring – CloudWatch provides near real-time monitoring, enabling you to track your OpenSearch Serverless collections’ performance as they operate. This immediate visibility allows for swift detection of anomalies or performance issues, enabling prompt response to potential problems.
  • Efficient error diagnosis – You can quickly identify and address common errors without extensive log analysis. For instance, by monitoring ingestion request errors, you can preemptively mitigate bulk indexing request failures.
  • Proactive alerting system – Use the CloudWatch alarm functionality in conjunction with Amazon Simple Notification Service (SNS) to set up custom alerts. By defining specific thresholds for critical metrics, you can receive instant notifications through email or SMS when your OpenSearch Serverless collections approach or exceed these limits.
  • Comprehensive historical analysis – The data retention capabilities of CloudWatch allow for in-depth historical analysis. This helps you to identify long-term performance trends, recognize recurring patterns in resource utilization and optimize workload distribution based on historical insights.

Solution overview

Understanding which metrics to monitor in OpenSearch Serverless helps optimize your system’s performance and reliability. This guide explains the key metrics to monitor, their significance, how to determine appropriate thresholds, and the step-by-step process for setting up alarms. Understanding these fundamentals will help you establish effective monitoring for your OpenSearch Serverless collections and help maintain optimal performance and reliability.

Prerequisites

Before getting started, you must have the following prerequisites:

CloudWatch metrics and recommended alarms for OpenSearch Serverless

The following table summarizes key CloudWatch metrics for OpenSearch Serverless, including recommended alarm thresholds, metric descriptions, and applicable workload types.

Alarm Metric Level Metric Description Alarm Description Use case
IndexingOCU maximum is >= 10 for 5 minutes, three consecutive times Account Level

Serverless compute capacity is measured in OpenSearch Compute Units (OCUs). Each OCU is a combination of 6 GiB of memory and corresponding virtual CPU (vCPU), in addition to data transfer to Amazon Simple Storage Service (Amazon S3).

The IndexingOCU metric reports the number of OCUs used for data ingestion across all collections.

This alarm will alert you when Indexing OCUs scale upto / beyond 10 for more than 15 minutes. Monitor and Optimize Costs
SearchOCU maximum is >= 10 for 5 minutes, three consecutive times Account Level

Serverless compute capacity is measured in OCUs. Each OCU is a combination of 6 GiB of memory and corresponding virtual CPU (vCPU), in addition to data transfer to Amazon S3.

The SearchOCU metric reports the number of OCUs used to search collection data across all collections.

This alarm will alert you when Search OCUs scale upto / beyond 10 for more than 15 minutes. Monitor and Optimize Costs
IngestionRequestLatency maximum is >= 3 secs for 1 minutes, five consecutive times. Collection Level The IngestionRequestLatency metric reports the latency, in seconds, for bulk write operations to a collection. This alarm monitors the maximum latency of bulk write operations to a collection. It triggers when the maximum IngestionRequestLatency exceeds 3 seconds for five consecutive 1-minute intervals (for a total of 5 minutes). This indicates a sustained performance degradation in data ingestion operations, which could impact application performance and data availability. This metric might be crucial to monitor for log-based workloads, where indexing time is critical.
SearchRequestLatency maximum is >= 2 secs for 1 minutes, five consecutive times. Collection Level The SearchRequestLatency metric reports the latency, in seconds, that it takes to complete a search operation against a collection. This alarm monitors the maximum latency of search operations against a collection. It triggers when the maximum SearchRequestLatency exceeds 2 seconds for five consecutive 1-minute intervals (for a total of 5 minutes). Consistently high search latency indicates performance issues that could degrade user experience and application responsiveness. This metric might be crucial to monitor for vector and search-based workloads, where search time is critical.
IngestionRequestErrors sum is >= 100 errors for 1 minute, five consecutive times Collection Level The IngestionRequestErrors metric reports the total number of bulk indexing request errors to a collection. OpenSearch Serverless emits this metric when there are bulk indexing request failures, such as an authentication or availability issue. This alarm monitors the total count of failed bulk indexing operations to a collection. It triggers when the number of IngestionRequestErrors equals or exceeds 100 errors for five consecutive 1-minute intervals (for a total of 5 minutes). Persistent ingestion errors indicate systemic issues that could lead to data loss or inconsistency.
SearchRequestErrors sum is >= 50 errors for 1 minute, five consecutive times Collection Level The SearchRequestErrors metric reports the total number of query errors per minute for a collection. This alarm monitors the total count of failed search query operations in a collection. It triggers when the number of SearchRequestErrors equals or exceeds 50 errors for five consecutive 1-minute intervals (for a total of 5 minutes). Persistent search errors indicate potential issues that could impact application functionality and user experience.
ActiveCollection minimum is 0 for 1 minutes, three consecutive times. Collection Level This metric indicates whether a collection is active. A value of 1 means that the collection is in an ACTIVE state. This value is emitted upon successful creation of a collection and remains 1 until you delete the collection. The metric can’t have a value of 0. The alarm triggers when the metric is missing for three consecutive 1-minute intervals (for a total of 3 minutes). Because an active collection always emits a value of 1, missing data indicates the collection has been deleted or is experiencing serious issues.
Note: Make sure to setup the CloudWatch alarm so that it will treat missing data as breaching.
Monitor Availability of Collection

The specific threshold values mentioned are examples. However, you may need to adjust these thresholds based on the unique requirements and SLAs of your own applications and workloads running on OpenSearch Serverless.

To decide when to raise the global OCU limits, you should regularly review the IndexingOCU and SearchOCU metrics at the account level. If you notice the metrics consistently approaching the set threshold, it’s a good indication that you should consider increasing the overall account limits to accommodate your growing usage.

Additionally, monitor the collection-level metrics like IngestionRequestLatency and SearchRequestLatency. If you notice certain collections have consistently high latency, it might be a sign that the OCU allocation for those specific collections is insufficient. In such cases, you could consider increasing the OCU limits for those high-usage collections, rather than raising the global account limits.

By closely monitoring both the account-level and collection-level metrics, you can make informed decisions about when and how to adjust your OCU limits to maintain optimal performance and cost efficiency for your OpenSearch Serverless deployment.

Steps to create a CloudWatch alarm

CloudWatch Alarms can be created using any of the following methods:

Detailed steps and a / sample code snippet for each method are provided in the following sections.

Using the console

The AWS Management Console provides a user-friendly, visual interface for creating CloudWatch alarms. Follow these step-by-step instructions to set up your alarm through the console.

  1. Navigate to the CloudWatch console
  2. In the navigation pane, choose Alarms and then, All alarms.
  3. Choose Create alarm.

Create an alarm

  1. Choose Select Metric.
  2. Select the namespace AOSS 

Choose CloudWatch Namespace

  1. To setup alerting on IndexingOCU across all collections, navigate to ClientId and select the metric.
  2. Under Conditions:
    1. For Statistic: Select Maximum.
    2. For Period: Select 5 minutes.
    3. For Threshold type: Choose Static and Greater.

Specify metric and conditions

  1. Choose Next. Under Notification, select an SNS topic to notify when the alarm is in ALARM state, OK state, or INSUFFICIENT_DATA state.

Configure Actions

  1. When finished, choose Next. Enter a name and description for the alarm. The name must contain only UTF-8 characters, and can’t contain ASCII control characters. The description can include markdown formatting, which is displayed only in the alarm Details tab in the CloudWatch console. The markdown can be useful to add links to runbooks or other internal resources. Then choose Next.
  2. Under Preview and create, confirm that the information and conditions are what you want, then choose Create alarm.

For detailed documentation, refer to Create a CloudWatch alarm based on a static threshold.

Using the AWS CLI

For those who prefer command-line interfaces or need to automate alarm creation, the AWS CLI offers an efficient alternative. This section demonstrates how to create a CloudWatch alarm using a single CLI command.

To set up a CloudWatch alarm using the AWS CLI, you can use the put-metric-alarm command. The following example demonstrates how to create an alarm that sends an Amazon SNS email when the IndexingOCU exceeds 2 for 15 minutes at the account level. Replace [region] and [account-id] with your AWS Region and account ID.

aws cloudwatch put-metric-alarm \
--alarm-description '# IndexingOCU scaling out' \
--actions-enabled \
--alarm-actions 'arn:aws:sns:[region]:[account-id]:SecurityHubRecurringSummary' \
--metric-name 'IndexingOCU' \
--namespace 'AWS/AOSS' \
--statistic 'Maximum' \
--dimensions '[{"Name":"ClientId","Value":"[account-id]"}]' \
--period 300 \
--evaluation-periods 3 \
--datapoints-to-alarm 3 \
--threshold 2 \
--comparison-operator 'GreaterThanThreshold' \
--treat-missing-data 'ignore'

CloudFormation JSON

Infrastructure as Code (IaC) enables version-controlled, repeatable deployments. This JSON template shows how to define a CloudWatch alarm using AWS CloudFormation, suitable for those who prefer JSON syntax for their IaC implementations.

Replace [region] and [account-id] with your AWS Region and account ID.

{
    "Type": "AWS::CloudWatch::Alarm",
    "Properties": {
        "AlarmDescription": "# IndexingOCU scaling out",
        "ActionsEnabled": true,
        "OKActions": [],
        "AlarmActions": [
            "arn:aws:sns:[region]:[account-id]:SecurityHubRecurringSummary"
        ],
        "InsufficientDataActions": [],
        "MetricName": "IndexingOCU",
        "Namespace": "AWS/AOSS",
        "Statistic": "Maximum",
        "Dimensions": [
            {
                "Name": "ClientId",
                "Value": "[account-id]"
            }
        ],
        "Period": 300,
        "EvaluationPeriods": 3,
        "DatapointsToAlarm": 3,
        "Threshold": 2,
        "ComparisonOperator": "GreaterThanThreshold",
        "TreatMissingData": "ignore"
    }
}

CloudFormation YAML

For teams that prefer YAML’s more readable format, this section provides the equivalent CloudFormation template in YAML. The template creates the same CloudWatch alarm with identical configurations as the JSON version.

Replace [region] and [account-id] with your AWS Region and account ID.

Type: AWS::CloudWatch::Alarm
Properties:
    AlarmDescription: "# IndexingOCU scaling out"
    ActionsEnabled: true
    OKActions: []
    AlarmActions:
        - arn:aws:sns:[region]:[account-id]:SecurityHubRecurringSummary
    InsufficientDataActions: []
    MetricName: IndexingOCU
    Namespace: AWS/AOSS
    Statistic: Maximum
    Dimensions:
        - Name: ClientId
          Value: "[account-id]"
    Period: 300
    EvaluationPeriods: 3
    DatapointsToAlarm: 3
    Threshold: 2
    ComparisonOperator: GreaterThanThreshold
    TreatMissingData: ignore

CloudWatch dashboards

You can use Amazon CloudWatch dashboards to monitor multiple resources in a unified view. For example, the following dashboard provides a consolidated view of OpenSearch Serverless OCU usage, helping you track and manage costs.

View dashboards

Clean up

To avoid incurring unintended future charges, delete the following resources that were created as part of solution walk-through of this post:

  • CloudWatch alarms
  • CloudFormation stacks
  • SNS topics

Conclusion

Effective monitoring helps maintain optimal performance and reliability of your OpenSearch Serverless collections. By implementing the CloudWatch alarms and monitoring strategies outlined in this post, you can work towards proactively identifying and responding to performance issues before they impact your applications, optimize costs by tracking OCU usage patterns, support high availability objectives by monitoring collection health and error rates, and help maintain consistent performance through latency monitoring. Remember that the thresholds suggested in this guide serve as a starting point, you should adjust them based on your specific use cases, performance requirements, and budget constraints. Regular review and refinement of these alarms will help you maintain an efficient and cost-effective OpenSearch Serverless deployment.

Related links

Monitoring Amazon OpenSearch Serverless

Create a CloudWatch alarm based on a static threshold


About the authors

Urmila Iyer

Urmila Iyer

Urmila is a Technical Account Manager at AWS, where she partners with enterprise customers to understand their business objectives and architect solutions that drive meaningful outcomes. With 15 years of experience in IT, including 6 years at AWS, she specializes in data-driven solutions, bringing enthusiasm and expertise to data analytics projects using OpenSearch and real-time analytics platforms.

Parth Shah

Parth Shah

Parth is a Senior Solutions Architect at AWS passionate about solving complex data challenges for strategic customers. As a analytics enthusiast, he helps organizations make sense of their data through innovative cloud solutions, with deep expertise in OpenSearch implementations.
Outside of work, he enjoys spending time with family, exploring different cuisines and playing cricket.

Trellix achieved 35% cost savings and enhanced security with Amazon OpenSearch Service

Post Syndicated from Leeneksh Dubey original https://aws.amazon.com/blogs/big-data/trellix-achieved-35-cost-savings-and-enhanced-security-with-amazon-opensearch-service/

This is a guest post by Leeneksh Dubey, Cloud Engineer at Trellix, in partnership with AWS.

Trellix, a global leader in cybersecurity solutions, emerged in 2022 from the merger of McAfee Enterprise and FireEye. Serving over 40,000 enterprise customers worldwide, Trellix delivers the industry’s most comprehensive, open, and native AI-powered security platform. Their solution helps organizations build operational resilience against advanced threats through automated detection, investigation, and response capabilities.

Today security teams face an increasingly complex landscape of cybersecurity threats, while the volume of security and application logs grows exponentially. With limited resources and personnel, teams struggle to investigate all security events, potentially missing emerging threats. Trellix addresses these challenges by unifying security tools across endpoints, networks, cloud, and email into a single, AI-powered platform. By automating threat detection, investigation, and response, it enables security teams to identify and neutralize threats faster while reducing operational complexity.

To address exponential log growth across their multi-tenant, multi-Region infrastructure, Trellix used Amazon OpenSearch Service, Amazon OpenSearch Ingestion, and Amazon Simple Storage Service (Amazon S3) to modernize their log infrastructure. Facing challenges with self-managed Elasticsearch clusters on Amazon Elastic Compute Cloud (Amazon EC2), Trellix’s migration to managed OpenSearch Service significantly optimized their operations. This strategic implementation enabled them to process terabytes of daily security data across multiple AWS Regions while achieving a 35% reduction in storage costs as of Q3 2024. The shift to managed services saved up to 10 hours of infrastructure maintenance time weekly, helping developers focus more on value-added tasks.

In this post, we share how, by adopting these AWS solutions, Trellix enhanced their system’s performance, availability, and scalability while reducing operational overhead.

Solution overview

Trellix’s innovative log management solution, built on AWS services, addresses the challenges of processing large volumes of security data across multiple Regions. This enterprise-grade architecture demonstrates how organizations can effectively manage security logs at scale while optimizing costs. The solution addresses three critical business challenges: efficient management of long-term log storage, scalable distribution of analytics and alerting functions, and optimization of storage costs across their multi-regional infrastructure. The architecture is illustrated in the following diagram, demonstrating how Trellix managed the security logs at scale while optimizing costs.

The Trellix security log management solution on AWS implements a comprehensive data pipeline that seamlessly handles log ingestion, processing, storage, and analysis. In the following sections, we explore the six steps of the workflow in more detail.

Step 1: Load data to Amazon S3

The solution begins with a data ingestion process using the Amazon S3 globally distributed and highly scalable infrastructure. Raw security and application logs are captured from multiple Regional deployments, helping Trellix maintain both data sovereignty and low latency access across various jurisdictions. These logs are then processed by the Trellix internal engine, which enriches them using proprietary security logic. This enriched dataset is subsequently stored back in Amazon S3, establishing a secure, scalable foundation for further security analytics and downstream processing.

Step 2: Amazon SNS notification triggered by S3 Events

After the enriched data is successfully stored in Amazon S3, the system initiates an event-driven automation sequence. Amazon S3 is configured to emit event notifications to an Amazon Simple Notification Service (Amazon SNS) topic whenever new data is uploaded. Amazon SNS acts as a notification hub, efficiently broadcasting these events to subscribed services or endpoints. This approach helps the architecture remain responsive and decoupled, because it allows various consumers to be alerted in real time as new data becomes available in the system.

Step 3: Message queuing in Amazon SQS

As the next step in the workflow, the SNS notifications are routed to Amazon Simple Queue Service (Amazon SQS), which serves as a durable and scalable queuing layer between producers and consumers. This queue acts as a buffer, facilitating reliable and asynchronous delivery of event metadata to downstream processing components. The use of Amazon SQS provides message persistence and fault tolerance, particularly under high-throughput or failure scenarios, allowing OpenSearch Ingestion to process incoming data in a controlled and resilient manner.

Step 4: Automated data processing with OpenSearch Ingestion

OpenSearch Ingestion continuously polls the SQS queue for new messages indicating the availability of data in Amazon S3. Upon receiving these messages, it uses its built-in integration capabilities to fetch the corresponding data directly from Amazon S3. After the data is retrieved, the ingestion pipeline performs the necessary transformations before forwarding it to the OpenSearch Service domain. To facilitate optimal cost-efficiency and performance, Trellix selected OR1 instances types for their OpenSearch deployment. These instances offer a high memory-to-vCPU ratio and are specifically optimized for intensive indexing and search workloads, making them ideal for handling large-scale log analytics operations.

Step 5: Log lifecycle setup using Index State Management

To optimize storage usage and manage data retention, Trellix has implemented Index State Management (ISM) policies within the OpenSearch Service. These policies automate the lifecycle of ingested log data by transitioning it through defined stages based on age and access patterns. Initially, logs reside in the hot tier for up to 24 hours, enabling immediate access for real-time security analysis. As logs age beyond this threshold, they are automatically transitioned to the UltraWarm storage, which offers a more cost-effective storage option while keeping the data queryable. Finally, after the predefined retention period expires, the ISM policy deletes the data from the system. This fully automated lifecycle management approach balances performance, compliance, and cost-efficiency.

Step 6: Comprehensive monitoring and visualization

Using the extensive monitoring capabilities of Amazon CloudWatch, complemented by Trellix’s in-house automations using OpenSearch public APIs for custom monitoring, the solution provides end-to-end visibility through integrated visualization tools. OpenSearch Dashboards provides security teams with powerful log analysis and search capabilities, so they can dive deep into security events and identify potential threats. Additionally, the solution uses Amazon Managed Grafana to create customized dashboards that monitor both the data pipeline health and OpenSearch cluster performance.

This dual visualization approach delivers multiple benefits: real-time security event monitoring and analysis, comprehensive performance metrics across the infrastructure, automated alerting for rapid threat response, custom dashboard views for different security operations needs, and unified visibility across the multiple Regional deployments. The combined power of these tools creates a robust monitoring framework that helps Trellix maintain a strong security posture while facilitating optimal performance across their global infrastructure.This six-step implementation demonstrates how AWS services can be combined to create a scalable, cost-efficient security log management solution that processes terabytes of daily security data while maintaining high performance and operational efficiency.

Key benefits

Trellix’s implementation of OpenSearch Service as their logging solution delivered three significant advantages that transformed their security operations.

Simplified log management architecture

Trellix streamlined their security operations by implementing a cohesive log management architecture that avoids the complexity of managing multiple disparate tools. By using OpenSearch Ingestion, a fully managed serverless data pipeline, Trellix simplified their data pipeline for processing real-time security data. The integration with Managed Grafana provides a unified visualization layer, enabling security teams to focus on threat detection rather than infrastructure management.

Scalability and resilience

The implementation of OpenSearch Service enables Trellix to achieve unprecedented scalability and resilience in their security operations. Trellix’s architecture uses an OpenSearch Ingestion pipeline to provide effortless handling of sudden log volume spikes across multiple Regional deployments. OpenSearch Ingestion enables dynamic scaling with automated resource optimization, facilitating seamless capacity management as data volumes grow. This capability helps Trellix maintain consistent performance even during periods of increased security event logging. The solution also implements a robust Multi-AZ deployment strategy to maintain maximum resilience and continuous service availability. During self-healing testing, the architecture demonstrated impressive recovery times under 9 minutes when a node was rebooted, showcasing its ability to maintain business continuity even in case of node failure. The automated failover capabilities facilitate minimal disruption to security operations, so Trellix can maintain constant vigilance over their customers’ security posture. Lastly, the solution uses automated Amazon S3 backups combined with hourly snapshots for comprehensive point-in-time recovery capabilities. Each Region maintains additional customer data replicas, creating a multi-layered data protection strategy that maintains the integrity and availability of critical security information.

Effortless scalability with optimized cost

Trellix’s exponential growth in security data processing demanded a solution that could scale dynamically while maintaining cost-efficiency. The strategic implementation of Amazon S3 and OpenSearch Service with UltraWarm storage provided the foundation for this scalable architecture. UltraWarm, a fully managed warm storage tier for OpenSearch Service, revolutionized how Trellix manages their extensive security data across multiple Regions. The solution uses UltraWarm’s innovative architecture, which uses Amazon S3 for durable storage while maintaining fast query performance for security analysis. A key advantage of UltraWarm’s Amazon S3 backed architecture is the removal of index replicas, significantly reducing cluster size and associated costs while maintaining data durability.The intelligent log prioritization framework forms the backbone of Trellix’s data management strategy, categorizing incoming data based on security significance. This systematic approach enables efficient routing of P2 and P3 log sources, optimized processing paths for different security priorities, reduced load on primary SIEM infrastructure, and customized handling based on customer requirements. The implementation has proven particularly valuable for security log analytics, where historical data analysis is crucial for threat detection and compliance requirements.The implementation delivered substantial operational and financial benefits for Trellix. By combining priority-based routing and tiered storage management, the organization achieved a 35% reduction in storage and compute costs while maintaining high-performance security operations. The solution enables efficient storage and analysis of extensive historical data, supporting Trellix’s commitment to comprehensive security monitoring while optimizing operational costs. This implementation demonstrates how AWS services can help organizations optimize costs without compromising security capabilities or operational efficiency.

What’s next

The successful implementation of this solution has positioned Trellix to explore additional AWS capabilities and emerging technologies to enhance their security operations:

  • Integration of AWS ML/AI services to analyze petabytes of security log data
  • Implementation of ML-based anomaly detection within OpenSearch Service
  • Using security analytics plugins for advanced threat detection
  • Custom configurations and pre-built security rules implementation

Summary

Trellix successfully modernized its log management infrastructure through collaboration with AWS, implementing a sophisticated architecture that addresses the challenges of processing terabytes of daily security data across multiple Regions. By using OpenSearch Service with UltraWarm nodes and integrating Amazon S3, the solution delivered significant performance enhancements, including faster log ingestion and streamlined operational management. The architecture’s innovative tiered storage approach, combined with optimized retention policies, resulted in a 35% reduction in storage costs while maintaining compliance requirements.This transformation has positioned Trellix to efficiently handle growing data volumes and evolving security challenges, demonstrating how strategic use of cloud services can simultaneously improve performance, reduce costs, and enhance operational efficiency.


About the authors

Leeneksh Dubey

Leeneksh Dubey

Leeneksh is a Cloud Engineer at Trellix, with expertise in architecting scalable and resilient cloud infrastructure on AWS. He works extensively across data, analytics, and Al workloads covering end-to-end solution design, deployment automation, and cost optimization. His focus is on building secure, high-performance environments that support the company’s cybersecurity product portfolio.

Harsh Bansal

Harsh Bansal

Harsh is an Analytics and AI Solutions Architect with Amazon Web Services. Bansal collaborates closely with clients, assisting in their migration to cloud platforms and optimizing cluster setups to enhance performance and reduce costs. Before joining AWS, Bansal supported clients in leveraging OpenSearch and Elasticsearch for diverse search and log analytics requirements.

Prashant Agrawal

Prashant Agrawal

Prashant is a Sr. Search Specialist Solutions Architect with Amazon OpenSearch Service. He works closely with customers to help them migrate their workloads to the cloud and helps existing customers fine-tune their clusters to achieve better performance and save on cost. Before joining AWS, he helped various customers use OpenSearch and Elasticsearch for their search and log analytics use cases. When not working, you can find him traveling and exploring new places. In short, he likes doing Eat → Travel → Repeat.

Announcing cross-account ingestion for Amazon OpenSearch Service

Post Syndicated from David Venable original https://aws.amazon.com/blogs/big-data/announcing-cross-account-ingestion-for-amazon-opensearch-service/

Amazon OpenSearch Ingestion is a powerful data ingestion pipeline that AWS customers use for many different purposes, such as observability, analytics, and zero-ETL search. Many customers today push logs, traces, and metrics from their applications to OpenSearch Ingestion to store and analyze this data.

Today, we are happy to announce that OpenSearch Ingestion pipelines now support cross-account ingestion for push-based sources such as HTTP and OpenTelemetry (OTel). Organizations can now use this feature to effortlessly share data across teams. For example, many organizations have central observability teams—now these teams can create OpenSearch Ingestion pipelines and share them with other teams in their organization. You can also use this feature to ingest data into Amazon OpenSearch Service domains or Amazon OpenSearch Serverless collections in other accounts.

Previously, sharing OpenSearch Ingestion pipelines across accounts required teams to use virtual private cloud (VPC) features to share access. For example, teams could use VPC peering, which is not always feasible, or AWS Transit Gateway. The new cross-account ingestion features in OpenSearch Ingestion can simplify your deployment and reduce cost for sharing pipelines.

Solution overview

Let’s look at how to share a pipeline from a central logging account with two other development accounts (A and B). The central logging account can create an OpenSearch Ingestion pipeline using a push-based source, for example, HTTP. After creating the pipeline, a member of the central logging team can grant access to the other teams. They can use a resource policy that gives permissions to the two other team accounts to create pipeline endpoints. After making this change, the OpenSearch Ingestion pipeline is available for use by the other teams.

The following diagram illustrates this configuration.

In the following sections, we demonstrate how to implement this solution.

Prerequisites

First, the central logging account must have a VPC with two options enabled.

  • enableDnsSupport must be set to true
  • enableDnsHostnames must be set to true

The central logging account must also create a push-based OpenSearch Ingestion pipeline in the VPC. This can be a pipeline receiving logs from FluentBit or OpenTelemetry telemetry.

The development accounts that are going to connect to the pipeline also must have VPCs in the same region with the same DNS options enabled.

  • enableDnsSupport must be set to true
  • enableDnsHostnames must be set to true

Create resource policy

As the owner of the pipeline, you can create a resource policy that allows the two development accounts to create pipeline endpoints against your pipeline.

The following is an example resource policy for this scenario:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "AWS": [
          "000000000000",
          "999999999999"
        ]
      },
      "Action": "osis:CreatePipelineEndpoint",
      "Resource": "arn:aws:osis:us-west-2:123456789012:pipeline/central-logging"
    }
  ]
}

The OpenSearch Ingestion console makes it straightforward to create these policies, as shown in the following screenshot.

Create pipeline endpoint

Now that the central logging account has shared permissions on their pipeline, the development accounts can create pipeline endpoints. A pipeline endpoint is a connection from one VPC to an OpenSearch Ingestion pipeline.

The development accounts are responsible for creating the pipeline endpoints in the VPCs they want to connect from. They create this in the subnets they need and provide a security group. The security group should have an inbound rule allowing access port HTTPS over port 443 from any source that the development accounts need to ingest logs.

Development team A can create a pipeline endpoint using a command similar to the following:

aws --region us-west-2 osis create-pipeline-endpoint \
--pipeline-arn arn:aws:osis:us-west-2:123456789012:pipeline/central-logging \
--vpc-options '{"SubnetIds":["subnet-123456789012345678","subnet-012345678912345678"],"SecurityGroupIds":["sg-123456789012345678"]}'

Development team A can also use the OpenSearch Ingestion console to create the pipeline endpoint.

After performing this change, the VPC for development team A will have a pipeline endpoint. This pipeline endpoint now allows for ingesting data into the central logging pipeline. Now, Amazon Elastic Compute Cloud (Amazon EC2) instances, Amazon Elastic Container Service (Amazon ECS) tasks, Kubernetes pods, and other compute running in the VPC can ingest their log data into the pipeline using tools such as FluentBit.

At the same time or at a later time, development team B can create a pipeline endpoint as well. This team will create it for their own VPC.

After this, the pipeline will now have two pipeline endpoints, so both teams can ingest their log data into the central logging VPC.

Clean up

After a pipeline endpoint is created, either account can remove it. The development teams in our scenario can use the DeletePipelineEndpoint API to delete it from their accounts. Additionally, if the central logging account needs to remove a pipeline endpoint from a pipeline, it can use the RevokePipelineEndpointConnections API. Both options are available on the OpenSearch Ingestion console as well.

After the pipeline endpoints are removed, the central logging team can also remove the pipeline if they no longer need it.

Conclusion

The new pipeline endpoint feature for OpenSearch Ingestion simplifies how you can share pipelines for cross-account ingestion. This can help teams use the powerful features of OpenSearch Ingestion and open up new possibilities for teams or organizations using multiple accounts and VPCs. The new pipeline endpoint feature is available today in AWS Regions where OpenSearch Ingestion is available.

To get started with cross-account ingestion in OpenSearch Ingestion, refer to OpenSearch Ingestion documentation or try creating your first cross-account pipeline on the OpenSearch Ingestion console.


About the authors

David Venable

David Venable

David is a senior software engineer working on observability in OpenSearch at Amazon Web Services. He is a maintainer on the Data Prepper project.

Get started with Amazon OpenSearch Service: T-shirt size your domain for log analytics

Post Syndicated from Harsh Bansal original https://aws.amazon.com/blogs/big-data/get-started-with-amazon-opensearch-service-t-shirt-size-your-domain-for-log-analytics/

When you’re spinning up your Amazon OpenSearch Service domain, you need to figure out the storage, instance types, and instance count; decide the sharding strategies and whether to use a cluster manager; and enable zone awareness. Generally, we consider storage as a guideline for determining instance count, but not other parameters. In this post, we offer some recommendations based on T-shirt sizing for log analytics workloads.

Log analytics and streaming workload characteristics

When you use OpenSearch Service for your streaming workloads, you send data from one or more sources into OpenSearch Service. OpenSearch Service indexes your data in an index that you define.

Log data naturally follows a time series pattern, and therefore a time-based indexing strategy (daily or weekly indexes) is recommended. For efficient management of log data, you must implement time-based index patterns and set retention periods. You further define time slicing and a retention period for the data to manage its lifecycle in your domain.

For illustration, consider that you have a data source producing a continuous stream of log data, and you’ve configured a daily rolling index and set a retention period of 3 days. As the logs arrive, OpenSearch Service creates an index per day with names like stream1_2025.05.21, stream1_2025.05.22, and so on. The prefix stream1_* is what we call an index pattern, a naming convention that helps group-related indexes.

The following diagram shows three primary shards for each daily index. These shards are deployed across three OpenSearch Service data instances, with one replica for each primary shard. (For simplicity, the diagram doesn’t show that primary and replica shards are always placed on different instances for fault tolerance.)

When OpenSearch Service processes new log entries, they are sent to all relevant primary shards and their replicas in the active index, which in this example is only today’s index due to the daily index configuration.

There are several important characteristics of how OpenSearch Service processes your new entries:

  • Total shard count – Each index pattern will have a D * P * (1 + R) total shards, where D represents retention in days, P represents primary shards, and R is the number of replicas. These shards are distributed across your data nodes.
  • Active index – Time slicing means that new log entries are only written to today’s index.
  • Resource utilization – When sending a _bulk request with log entries, these are distributed across all shards in the active index. In our example with three primary shards and one replica per shard, that’s a total of six shards processing new data simultaneously, requiring 6 vCPUs to efficiently handle a single _bulk request.

Similarly, OpenSearch Service distributes queries across the shards for the indexes involved. If you query this index pattern across all 3 days, you will engage 9 shards, and need 9 vCPUs to process the request.

This will get even more complicated when you add in more data streams and index patterns. For each additional data stream or index pattern, you deploy shards for each of the daily indexes and use vCPUs to process requests in proportion to the shards deployed, as shown in the preceding diagram. When you make concurrent requests to more than one index, each shard for all the indexes involved must process those requests.

Cluster capacity

As the number of index patterns and concurrent requests increases, you can quickly overwhelm the cluster’s resources. OpenSearch Service includes internal queues that buffer requests and mitigate this concurrency demand. You can monitor these queues using the _cat/thread_pool API, which shows queue depths and helps you understand when your cluster is approaching capacity limits.

Another complicating dimension is that the time to process your updates and queries depends on the contents of the updates and queries. As requests come in, the queues are filling at the rate you are sending them. They are draining at a rate that is governed by the available vCPUs, the time they take on each request, and the processing time for that request. You can interleave more requests if those requests clear in a millisecond than if they clear in a second. You can use the _nodes/stats OpenSearch API to monitor average load on your CPUs. For more information about the query phases, refer to A query, or There and Back Again on the OpenSearch blog.

If you see the queue depths increasing, you are moving into a “warning” area, where the cluster is handling load. But if you continue, you can start to exceed the available queues and must scale to add more CPUs. If you start to see load increasing, which is correlated with queue depth increasing, you are also in a “warning” area and should consider scaling.

Recommendations

For sizing a domain, consider the following steps:

  • Determine the storage required – Total storage = (daily source data in bytes × 1.45) × (number_of_replicas + 1) × number of days retained. This accounts for the additional 45% overhead on daily source data, broken down as follows:
    • 10% for larger index size than source data.
    • 5% for operating system overhead (reserved by Linux for system recovery and disk defragmentation protection).
    • 20% for OpenSearch reserved space per instance (segment merges, logs, and internal operations).
    • 10% for additional storage buffer (minimizes impact of node failure and Availability Zone outages).
  • Define the shard count – Approximate number of primary shards = storage size required per index / desired shard size. Round up to the nearest multiple of your data node count to maintain even distribution. For more detailed guidance on shard sizing and distribution strategies, refer to “Amazon OpenSearch Service 101: How many shards do I need” For log analytics workloads, consider the following:
    • Recommended shard size: 30–50 GB
    • Optimal target: 50 GB per shard
  • Calculate CPU requirements – Recommended ratio is 1.25 vCPU:1 Shard for lower data volumes. Higher ratios are recommended for larger volumes. Target utilization is 60% average, 80% maximum.
  • Choose the right instance type – Consider the following based on your nodes:

Let’s look at an example for domain sizing. The initial requirements are as follows:

  • Daily log volume: 3 TB
  • Retention period: 3 months (90 days)
  • Replica count: 1

We make the following instance calculation.

The following table recommends instances, amount of source data, storage needed for 7 days of retention, and active shards based on the preceding guidelines.

T-Shirt Size Data (Per Day) Storage Needed (with 7 days Retention) Active Shards Data Nodes Primary Nodes
XSmall 10 GB 175 GB 2 @ 50 GB 3 * r7g.large. search 3 * m7g.large. search
Small 100 GB 1.75 TB 6 @ 50 GB 3 * r7g.xlarge. search 3 * m7g.large. search
Medium 500 GB 8.75 TB 30 @ 50 GB 6 * r7g.2xlarge.search 3 * m7g.large. search
Large 1 TB 17.5 TB 60 @ 50 GB 6 * r7g.4xlarge.search 3 * m7g.large. search
XLarge 10 TB 175 TB 600 @ 50 GB 30 * i4g.8xlarge 3 * m7g.2xlarge.search
XXL 80 TB 1.4 PB 2400 @ 50 GB 87 * I4g.16xlarge 3 * m7g.4xlarge.search

As with all sizing recommendations, these guidelines represent a starting point and are based on assumptions. Your workload will differ, and so your actual needs will differ from these recommendations. Make sure to deploy, monitor, and adjust your configuration as needed.

For T-shirt sizing the workloads, an extra-small use case encompasses 10 GB or less of data per day from a single data stream to a single index pattern. A small use case falls between 10–100 GB per day of data, a medium use case between 100–500 GB of data, and so on. Default instance count per domain is 80 for most of the instance family. Refer to the “Amazon OpenSearch Service quotas “ for details.

Additionally, consider the following best practices:

Conclusion

This post provided comprehensive guidelines for sizing your OpenSearch Service domain for log analytic workloads, covering several critical aspects. These recommendations serve as a solid starting point, but each workload has unique characteristics. For optimal performance, consider implementing additional optimizations like data tiering and storage tiers. Evaluate cost-saving options such as reserved instances, and scale your deployment based on actual performance metrics and queue depths.By following these guidelines and actively monitoring your deployment, you can build a well-performing OpenSearch Service domain that meets your log analytics needs while maintaining efficiency and cost-effectiveness.


About the authors

Harsh Bansal

Harsh Bansal

Harsh is an Analytics and AI Solutions Architect at Amazon Web Services. Bansal collaborates closely with clients, assisting in their migration to cloud platforms and optimizing cluster setups to enhance performance and reduce costs. Before joining AWS, Bansal supported clients in leveraging OpenSearch and Elasticsearch for diverse search and log analytics requirements.

Aditya Challa

Aditya Challa

Aditya is a Senior Solutions Architect at Amazon Web Services. Aditya loves helping customers through their AWS journeys because he knows that journeys are always better when there’s company. He’s a big fan of travel, history, engineering marvels, and learning something new every day.

Raaga NG

Raaga NG

Raaga is a Solutions Architect at Amazon Web Services. Raaga is a technologist with over 5 years of experience specializing in Analytics. Raaga is passionate about helping AWS customers navigate their journey to the cloud.

Decrease your storage costs with Amazon OpenSearch Service index rollups

Post Syndicated from Luis Tiani original https://aws.amazon.com/blogs/big-data/decrease-your-storage-costs-with-amazon-opensearch-service-index-rollups/

Amazon OpenSearch Service is a fully managed service to support search, log analytics, and generative AI Retrieval Augment Generation (RAG) workloads in the AWS Cloud. It simplifies the deployment, security, and scaling of OpenSearch clusters. As organizations scale their log analytics workloads by continuously collecting and analyzing vast amounts of data, they often struggle to maintain quick access to historical information while managing costs effectively. OpenSearch Service addresses these challenges through its tiered storage options: hot, UltraWarm, and cold storage. These storage tiers are great options to help optimize costs and offer a balance between performance and affordability, so organizations can manage their data more efficiently. Organizations can choose between these different storage tiers by keeping data in expensive hot storage for quick access or moving it to cheaper cold storage with limited accessibility. This trade-off becomes particularly challenging when organizations need to analyze both recent and historical data for compliance, trend analysis, or business intelligence.

In this post, we explore how to use index rollups in Amazon OpenSearch Service to address this challenge. This feature helps organizations efficiently manage their historical data by automatically summarizing and compressing older data while maintaining its analytical value, significantly reducing storage costs in any storage tier without sacrificing the ability to query historical information effectively.

Index rollups overview

Index rollups provide a mechanism to aggregate historical data into summarized indexes at specified time intervals. This feature is particularly useful for time series data where the granularity of older data can be reduced while maintaining meaningful analytics capabilities.

Key benefits include:

  • Reduced storage costs (varies by granularity level), for example:
    • Larger savings when aggregating from seconds to hours
    • Moderate savings when aggregating from seconds to minutes
  • Improved query performance of historical data
  • Maintained data accessibility for long-term analytics
  • Automated data summarization process

Index rollups are part of a comprehensive data management strategy. The real cost savings come from properly managing your data lifecycle in conjunction with rollups. To achieve meaningful cost reductions, you must remove or move the original data to a lower-cost storage tier after creating the rollup.

For customers already using Index State Management (ISM) to move older data to UltraWarm or cold tiers, rollups can provide significant additional benefits. By aggregating data at higher time intervals before moving it to lower-cost tiers, you can dramatically reduce the volume of data in these tiers, leading to further cost savings. This strategy is particularly effective for workloads with large amounts of time series data, typically measuring in terabytes or petabytes. The larger your data volume, the more impactful your savings will be when implementing rollups correctly.

Index rollups can be implemented using ISM policies through the OpenSearch Dashboards UI or the OpenSearch API. Index rollups require OpenSearch or Elasticsearch 7.9 or later.

The decision to use different storage tiers requires careful consideration of an organization’s specific needs, balancing the desire for cost savings with the requirement for data accessibility and performance. As data volumes continue to grow and analytics become increasingly important, finding the right storage strategy becomes crucial for businesses to remain competitive and compliant while managing their budgets effectively.

In this post, we consider a scenario with a large volume of time series data that can be aggregated using the Rollup API. With rollups, you have the flexibility to either store aggregated data in the hot tier for rapid access or aggregate and promote it to more cost-effective tiers such as UltraWarm or cold storage. This approach allows for efficient data and index lifecycle management while optimizing both performance and cost.

Index rollups are often confused with index rollovers, which are automated OpenSearch Service operations that create new indexes when specified thresholds are met, for example by age, size, or document count. This feature maintains raw data while optimizing cluster performance through controlled index growth. For example, rolling over when an index reaches 50 GB or is 30 days old.

Use cases for index rollups

Index rollups are ideal for scenarios where you need to balance storage costs with data granularity, such as:

  • Time series data that requires different granularity levels over time – For example, Internet of Things (IoT) sensor data where real-time precision matters only for the most recent data.
    • Traditional approach – It is common for users to keep all data in expensive hot storage for instant accessibility. However, this isn’t optimal for cost.
    • Recommended – Retain recent (per second) data in hot storage for immediate access. For older periods, store aggregated (hourly or daily) data using index rollups. Move or delete the higher-granularity old data from the hot tier. This balances accessibility and cost-effectiveness.
  • Historical data with cost-optimization needs – For example, system performance metrics where overall trends are more valuable than precise values over time.
    • Traditional approach – It is common for users to store all performance metrics at full granularity indefinitely, consuming excessive storage space. We don’t recommend storing data indefinitely. Implement a data retention policy based on your specific business needs and compliance requirements.
    • Recommended – Maintain detailed metrics for recent monitoring (last 30 days) and aggregate older data into hourly or daily summaries. This preserves the trend analysis capability while significantly reducing storage costs.
  • Log data with infrequent historical access and low value – For example, application error logs where detailed investigation is primarily needed for recent incidents.
    • Traditional approach – It is common for users to keep all log entries at full detail, regardless of age or access frequency.
    • Recommended – Preserve detailed logs for an active troubleshooting period (for example, 1 week) and maintain summarized error patterns and statistics for older periods. This enables historical pattern analysis while reducing storage overhead.

Schema design

A well-planned schema is crucial for successful rollup implementation. Proper schema design makes sure your rolled-up data remains valuable for analysis while maximizing storage savings. Consider the following key aspects:

  • Identify fields required for long-term analysis – Carefully select fields that provide meaningful insights over time, avoiding unnecessary data retention.
  • Define aggregation types for each field, such as min, max, sum, and average – Choose appropriate aggregation methods that preserve the analytical value of your data.
  • Determine which fields can be excluded from rollups – Reduce storage costs by omitting fields that don’t contribute to long-term analysis.
  • Consider mapping compatibility between source and target indexes – Provide successful data transition without mapping conflicts. This involves:
    • Matching data types (for example, date fields remain as date in rollups)
    • Handling nested fields appropriately
    • Ensuring all required fields are included in the rollup
    • Considering the impact of analyzed vs. non-analyzed fields
    • Incompatible mappings can lead to failed rollup jobs or incorrect data aggregation.

Functional and non-functional requirements

Before implementing index rollups, consider the following:

  • Data access patterns – When implementing data rollup strategies, it’s crucial to first analyze data access patterns, including query frequency and usage periods, to determine optimal rollup intervals. This analysis should lead to specific granularity metrics, such as deciding between hourly or daily aggregations, while establishing clear thresholds based on both data volume and query requirements. These decisions should be documented alongside specific aggregation rules for each data type.
  • Data growth rate – Storage optimization begins with calculating your current dataset size and its growth rate. This information helps quantify potential space reductions across different rollup strategies. Performance metrics, particularly expected query response times, should be defined upfront. Additionally, establish monitoring KPIs focusing on latency, throughput, and resource usage to make sure the system meets performance expectations.
  • Compliance or data retention requirements – Retention planning requires careful consideration of regulatory requirements and business needs. Develop a clear retention policy that specifies how long to keep different types of data at various granularity levels. Implement systematic processes for archiving or deleting older data and maintain detailed documentation of storage costs across different retention periods.
  • Resource utilization and planning – For successful implementation, proper cluster capacity planning is essential. This involves accurately sizing computing resources, including CPU, RAM, and storage requirements. Define specific time windows for executing rollup jobs to minimize impact on regular operations. Set clear resource utilization thresholds and implement proactive capacity monitoring. Finally, develop a scalability plan that accounts for both horizontal and vertical growth to accommodate future needs.

Operational requirements

Proper operational planning facilitates smooth ongoing management of your rollup implementation. This is essential for maintaining data reliability and system health:

  • Monitoring – You must monitor rollup jobs for their accuracy and desired results. This means implementing automated checks that validate data completeness, aggregation accuracy, and job execution status. Set up alerts for failed jobs, data inconsistencies, or when aggregation results fall outside expected ranges.
  • Scheduling hours – Schedule rollup operations during periods of low system usage, typically during off-peak hours. Document these maintenance windows clearly and communicate them to all stakeholders. Include buffer time for potential issues and establish clear procedures for what happens if a maintenance window needs to be extended.
  • Backup and recovery – OpenSearch Service takes automated snapshots of your data at 1-hour intervals. But you can define and implement comprehensive backup procedures using snapshot management functionality to support your Recovery Time Objective (RTO) and Recovery Point Objective (RPO).

Your RPO can be customized through different rollup schedules based on index patterns. This flexibility helps you define varied data loss tolerance levels according to your data’s criticality. For mission-critical indexes, you can configure more frequent rollups, while maintaining less frequent schedules for analytical data.

You can tailor RTO management in OpenSearch per index pattern through backup and replication options. For critical rollup indexes, implementing cross-cluster replication maintains up-to-date copies, significantly reducing recovery time. Other indexes might use standard backup procedures, balancing recovery speed with operational costs. This flexible approach helps you optimize both storage costs and recovery objectives based on your specific business requirements for different types of data within your OpenSearch deployment.

Before implementing rollups, audit all applications and dashboards that use the data being aggregated. Update queries and visualizations to accommodate the new data structure. Test these changes thoroughly in a staging environment to confirm they continue to provide accurate results with the rolled-up data. Create a rollback plan in case of unexpected issues with dependent applications.

In the following sections, we walk through the steps to create, run, and monitor a rollup job.

Create a rollup job

As discussed in previous sections, there are some considerations when choosing good candidates for index rollup usage. Building on this concept, identify your indexes to roll up their data and create the jobs.The following code is an example of creating a basic rollup job:

PUT /_plugins/_rollup/jobs/sensor_hourly_rollup
{
  "rollup": {
    "rollup_id": "sensor_1_hour_rollup",
    "enabled": true,
    "schedule": {
      "interval": {
        "start_time": 1746632400,        
        "period": 1,
        "unit": "hours",
        "schedule_delay": 0
      }
    },
    "description": "Rolls up sensor data 1 hourly per device_id",
    "source_index": "sensor-*",           
    "target_index": "sensor_rolled_hour",
    "page_size": 1000,
    "delay": 0,
    "continuous": true,
    "dimensions": [
      {
        "date_histogram": {
          "fixed_interval": "1h",
          "source_field": "timestamp",
          "target_field": "timestamp",
          "timezone": "UTC"
        }
      },
      {
        "terms": {
          "source_field": "device_id",
          "target_field": "device_id"
        }
      }
    ],
    "metrics": [
      {
        "source_field": "temperature",
        "metrics": [
          { "avg": {} },
          { "min": {} },
          { "max": {} }
        ]
      },
      {
        "source_field": "humidity",
        "metrics": [
          { "avg": {} },
          { "min": {} },
          { "max": {} }
        ]
      },
      {
        "source_field": "pressure",
        "metrics": [
          { "avg": {} },
          { "min": {} },
          { "max": {} }
        ]
      },
      {
        "source_field": "battery",
        "metrics": [
          { "avg": {} },
          { "min": {} },
          { "max": {} }
        ]
      }
    ]
  }
}

This rollup job processes IoT sensor data, aggregating readings from the sensor-* index pattern into hourly summaries stored in sensor_rolled_hour. It maintains device-level granularity while calculating average, minimum, and maximum values for temperature, humidity, pressure, and battery levels. The job executes hourly, processing 1,000 documents per batch.

The preceding code assumes that the device_id field is of type keyword; note that aggregation can’t be performed on the text field.

Start the rollup job

After you create the job, it will automatically be scheduled based on the job’s configuration (refer to the schedule: part of the job example code in the previous section). However, you can also trigger the job manually using the following API call:

POST _plugins/_rollup/jobs/sensor_hourly_rollup/_start

The following is an example of the results:

{
  "acknowledged": true
}

Monitor progress

Using Dev Tools, run the following command to monitor the progress:

GET _plugins/_rollup/jobs/sensor_hourly_rollup/_explain

The following is an example of the results:

{
  "sensor_hourly_rollup": {
    "metadata_id": "pCDjMZcBgTxYF90dWEfP",
    "rollup_metadata": {
      "rollup_id": "sensor_hourly_rollup",
      "last_updated_time": 1749043472416,
      "continuous": {
        "next_window_start_time": 1749043440000,
        "next_window_end_time": 1749043560000
      },
      "status": "started",
      "failure_reason": null,
      "stats": {
        "pages_processed": 374603,
        "documents_processed": 390,
        "rollups_indexed": 200,
        "index_time_in_millis": 789,
        "search_time_in_millis": 402202
      }
    }
  }
}  

The GET _plugins/_rollup/jobs/sensor_hourly_rollup/_explain command shows the current status and statistics of the sensor_hourly_rollup job. The response shows important statistics such as the number of processed documents, indexed rollups, time spent on indexing and searching, and records of any failures. The status indicates whether the job is active (started) or stopped (stopped) and shows the last processed timestamp. This information is crucial for monitoring the efficiency and health of the rollup process, helping administrators track progress, identify potential issues or bottlenecks, and confirm the job is operating as expected. Regular checks of these statistics can help in optimizing the rollup job’s performance and maintaining data integrity.

Real-world example

Let’s consider a scenario where a company collects IoT sensor data, ingesting 240 GB of data per day to an OpenSearch cluster, which totals 7.2 TB per month.

The following is an example record:

"_source": {
          "timestamp": "2024-01-01T10:00:00Z",
          "device_id": "sensor_001",
          "temperature": 26.1,
          "humidity": 43,
          "pressure": 1009.3,
          "battery": 90
}

Assume you have a time series index with the following configuration:

  • Ingest rate: 10 million documents per hour
  • Retention period: 30 days
  • Each document size: Approximately 1 KB

The total storage without rollups is as follows:

  • Per-day storage size: 10,000,000 docs per hour × ~1 KB × 24 hours per day = ~240 GB
  • Per-month storage size: 240 GB × 30 days = ~7.2 TB

The decision to implement rollups should be based on a cost-benefit analysis. Consider the following:

  • Current storage costs vs. potential savings
  • Compute costs for running rollup jobs
  • Value of granular data over time
  • Frequency of historical data access

For smaller datasets (for example, less than 50 GB/day), the benefits might be less significant. As data volumes grow, the cost savings become more compelling.

Rollup configuration

Let’s roll up the data with the following configuration:

  • From 1-minute granularity to 1-hour granularity
  • Aggregating average, min, and max, grouped by device_id
  • Reducing 60 documents per minute to 1 rollup document per minute

The new document count per hour is as follows:

  • Per-hour documents: 10,000,000/60 = 166,667 docs per hour
  • Assuming each rollup document is 2 KB (extra metadata), total rollup storage: 166,667 docs per hour × 24 hours per day × 30 days × 2KB ˜= 240 GB/month

Verify all required data exists in the new rolled index, then delete the original index to remove raw data manually or by using ISM policies (as discussed in the next section).

Execute the rollup job following the preceding instructions to aggregate data into the new rolled up index. To view your aggregated results, run the following code:

GET sensor_rolled_hour/_search
{
  "size": 0,
  "aggs": {
    "per_device": {
      "terms": {
        "field": "device_id",
        "size": 200,
        "shard_size": 200
      },
      "aggs": {
        "temperature_avg": {
          "avg": {
            "field": "temperature"
          }
        },
        "temperature_min": {
          "min": {
            "field": "temperature"
          }
        },
        "temperature_max": {
          "max": {
            "field": "temperature"
          }
        }
      }
      }
    }
  } 

The following code shows the example results:

"aggregations": {
    "per_device": {
      "doc_count_error_upper_bound": 0,
      "sum_other_doc_count": 0,
      "buckets": [
        {
          "key": "sensor_001",
          "doc_count": 98,
          "temperature_min": {
            "value": 24.100000381469727
          },
          "temperature_avg": {
            "value": 26.287754603794642
          },
          "temperature_max": {
            "value": 27.5
          }
        },
        {
          "key": "sensor_002",
          "doc_count": 98,
          "temperature_min": {
            "value": 20.600000381469727
          },
          "temperature_avg": {
            "value": 22.192856146364797
          },
          "temperature_max": {
            "value": 22.799999237060547
          }
        },...]

This document represents the rolled-up data for sensor_001 and sensor_002 during a 1-hour period. It aggregates 1 hour of sensor readings into a single record, storing minimum, average, and maximum values for temperature levels. The record includes metadata about the rollup process and timestamps for data tracking. This aggregated format significantly reduces storage requirements while maintaining essential statistical information about the sensor’s performance during that hour.

We can calculate the storage savings as follows:

  • Original storage: 7.2 TB (or 7200 GB)
  • Post-rollup storage: 240 GB
  • Storage savings: ((7.2 TB – 240 GB)/7.2 GB) × 100 = 96.67% savings

Using OpenSearch rollups as demonstrated in this example, you can achieve approximately 96% storage savings while preserving important aggregate insights.

The aggregation levels and document sizes can be customized according to your specific use case requirements.

Automate rollups with ISM

To fully realize the benefits of index rollups, automate the process using ISM policies. The following code is an example that implements a rollup strategy based on the given scenario:

PUT _plugins/_ism/policies/sensor_rollup_policy
{
  "policy": {
    "description": "Roll up sensor data and delete original",
    "default_state": "hot",
    "ism_template": {
      "index_patterns": ["sensor-*"],
      "priority": 100
    },
    "states": [
      {
        "name": "hot",
        "actions": [],
        "transitions": [
          {
            "state_name": "rollup",
            "conditions": {
              "min_index_age": "1d"
            }
          }
        ]
      },
      {
        "name": "rollup",
        "actions": [
          {
            "rollup": {
              "ism_rollup": {
                "target_index": "sensor_rolled_minutely",
                "description": "Rollup sensor data to minutely aggregations",
                "page_size": 1000,
                "dimensions": [
                  {
                    "date_histogram": {
                      "fixed_interval": "1m",
                      "source_field": "timestamp",
                      "target_field": "timestamp"
                    }
                  },
                  {
                    "terms": {
                      "source_field": "device_id",
                      "target_field": "device_id"
                    }
                  }
                ],
                "metrics": [
                  {
                    "source_field": "temperature",
                    "metrics": [{ "avg": {} }, { "min": {} }, { "max": {} }]
                  },
                  {
                    "source_field": "humidity",
                    "metrics": [{ "avg": {} }, { "min": {} }, { "max": {} }]
                  }
                ]
              }
            }
          }
        ],
        "transitions": [
          {
            "state_name": "delete",
            "conditions": {
              "min_index_age": "2d"
            }
          }
        ]
      },
      {
        "name": "delete",
        "actions": [
          {
            "delete": {}
          }
        ]
      }
    ]
  }
}

This ISM policy automates the rollup process and data lifecycle:

    1. Applies to all indexes matching the sensor-* pattern.
    2. Keeps original data in the hot state for 1 day.
    3. After 1 day, rolls up the data into minutely aggregations. Aggregates by device_id and calculates average, minimum, and maximum for temperature and humidity.
    4. Stores rolled-up data in the sensor_rolled_minutely index.
    5. Deletes the original index 2 days after rollup.

This strategy offers the following benefits:

  • Recent data is available at full granularity
  • Historical data is efficiently summarized
  • Storage is optimized by removing original data after rollup

You can monitor the policy’s execution using the following command:

GET _plugins/_ism/policies/sensor_rollup_policy

Remember to adjust the timeframes, metrics, and aggregation intervals based on your specific requirements and data patterns.

Conclusion

Index rollups in OpenSearch Service provide a powerful way to manage storage costs while maintaining valuable historical data access. By implementing a well-planned rollup strategy, organizations can achieve significant cost savings while making sure their data remains available for analysis.

To get started, take the following next steps:

  • Review your current index patterns and data retention requirements
  • Analyze your historical data volumes and access patterns
  • Start with a proof-of-concept rollup implementation in a test environment
  • Monitor performance and storage metrics to optimize your rollup strategy
  • Move the infrequently accessed data between storage tiers:
    • Delete data you’ll no longer use
    • Automate the process using ISM policies

To learn more, refer to the following resources:


About the authors

Luis Tiani

Luis Tiani

Luis is a Sr Solutions Architect at AWS. He specializes in data and analytics topics, with extensive focus on Amazon OpenSearch Service for search, log analytics, and vector environments. Tiani has helped numerous customers across financial services, DNB, SMB, and enterprise segments in their OpenSearch adoption journey, reviewing use cases and providing architecture design and cluster sizing guidance. As a Solutions Architect, he has worked with FSI customers in developing and implementing big data and data lake solutions, app modernization, cloud migrations, and AI/ML initiatives.

Muhammad Ali

Muhammad Ali

Muhammad is a Principal Analytics (APJ Tech Lead) at AWS with over 20 years of experience in the industry. He specializes in information retrieval, data analytics, and artificial intelligence, advocating an AI-first approach while helping organizations build data-driven mindsets through technology modernization and process transformation.

Srikanth Daggumalli

Srikanth Daggumalli

Srikanth is a Senior Analytics & AI Specialist Solutions Architect in AWS. He has over a decade of experience in architecting cost-effective, performant, and secure enterprise applications that improve customer reachability and experience, using big data, AI/ML, cloud, and security technologies. He has built high-performing data platforms for major financial institutions, enabling improved customer reach and exceptional experiences. He has also built many real-time streaming log analytics, SIEM, observability, and monitoring solutions to many AWS customers, including major financial institutions, enterprise, ISV, DNB, and more.

Implement fine-grained access control using Amazon OpenSearch Service and JSON Web Tokens

Post Syndicated from Ramya Bhat original https://aws.amazon.com/blogs/big-data/implement-fine-grained-access-control-using-amazon-opensearch-service-and-json-web-tokens/

This post demonstrates how to build a secure search application using Amazon OpenSearch Service and JSON Web Tokens (JWTs). We discuss the basics of OpenSearch Service and JWTs and how to implement user authentication and authorization through an existing identity provider (IdP). The focus is on enforcing fine-grained access control based on user roles and permissions.

JWT authentication and authorization for your OpenSearch Service domain provides a robust mechanism that addresses requirements for fine-grained access control. An IdP is a service that stores and manages user identities and their access rights, enabling centralized user authentication across multiple applications. The IdP issues JWTs, which are secure tokens containing claims about the authenticated user. By using JWTs from the IdP, you can:

  • Implement secure, role-based access control to search results
  • Validate user permissions before granting access to sensitive data
  • Maintain a centralized authentication mechanism across your search application
  • Make sure only authorized users can view data based on their predefined roles

The JWT integration helps organizations:

  • Define granular permissions within the IdP
  • Authenticate users using bearer tokens across different applications
  • Protect sensitive information through token-based access management
  • Reduce complexity of managing multiple authentication systems

Key benefits of the solution include:

  • Standardized token-based authentication
  • Centralized permission management
  • Simplified single sign-on (SSO) experience
  • Flexible and scalable access control mechanism

The ability to dynamically filter sensitive information based on token claims enhances data security while reducing the complexity of managing multiple authentication systems. This capability is made possible through the fine-grained access control (FGAC) feature in OpenSearch Service, which enforces document- and field-level access based on user roles.

Use case overview

In this post, we explore a user workflow with multiple roles and access level requirements. A research institution wants to build a secure search application with controlled access to biomedical databases specifically PubMed (a comprehensive database of biomedical literature) and Clinical Trials (a registry of medical research studies). Different research teams require varying levels of access to these datasets based on their roles and clearance levels. The following hierarchical access structure defines the user roles and their corresponding permission levels for accessing PubMed and Clinical Trials databases:

  • PubMed Admin – Full read access to all PubMed data (for senior research groups)
  • PubMed Limited – Restricted access to specific fields and documents (for researchers with limited access)
  • Clinical Trials Admin – Full read access to all Clinical Trials data (for principal investigators and senior trial managers)
  • Clinical Trials Limited – Restricted read access to specific trial information and aggregated data (for trial researchers with limited access)
  • Research Basic – Read-only access to specific public data in PubMed and Clinical Trials (for general research staff and interns)
  • Research Full Access – Full read and write access to all indices, with permissions to update or modify data

To implement this use case, we use JWTs generated by the supported IdP, which encode role-specific information. This setup makes sure OpenSearch Service can validate tokens before returning search results, dynamically filtering sensitive data based on the user’s JWT claims and fine-grained access control settings.

Solution overview

The technical workflow for using JWT authorization with OpenSearch Service involves several key stages:

  • User authentication – Users log in through the existing authentication system linked to the IdP
  • JWT generation – Upon successful authentication, the IdP generates a JWT containing specific role information
  • Search query submission – Users submit search queries to OpenSearch Service along with their JWT
  • Token validation – OpenSearch Service validates and decodes the JWT to verify user permissions
  • Result filtering – Search results are filtered based on the user’s permissions defined in the JWT
  • Data retrieval – Only authorized data is returned to the user, enforcing compliance with privacy standards

This workflow provides a standardized approach to authentication and authorization while streamlining user interactions with the search application. The solution makes sure each user sees only the information appropriate to their role, maintaining data privacy and organizational security standards.

You must enable JWT authentication and authorization, and fine-grained access control during the OpenSearch Service domain creation process. For more information, refer to Configuring JWT authentication and authorization and Fine-grained access control in Amazon OpenSearch Service.

The following diagram illustrates the solution architecture.

AWS architecture diagram showing authentication and search flow between services. The diagram shows integration with Amazon OpenSearch Service for queries and Amazon Cognito for authentication. The flow is marked with numbered steps (1-7) indicating the sequence of operations from client login through Cognito to executing authenticated OpenSearch queries.

This solution demonstrates authentication using Amazon Cognito as the IdP to generate the JWT. However, you can use another supported IdP. The ID token includes group membership information that OpenSearch Service maps to roles configured using fine-grained access control.

The user flow consists of the following steps:

  1. The client initiates authentication by logging in with Amazon Cognito user credentials. Amazon Cognito returns an authorization code.
  2. The client sends the authorization code to an Amazon API Gateway /token endpoint for ID token exchange.
  3. API Gateway forwards the authorization code to an AWS Lambda function.
  4. The Lambda function sends a token exchange request to Amazon Cognito with the authorization code.
  5. The Lambda function receives the ID token from Amazon Cognito and returns it to the client.
  6. The client sends an OpenSearch Service query to the API Gateway /search endpoint, including the ID token. API Gateway validates the ID token (JWT) with Amazon Cognito.
  7. API Gateway forwards the request to a Lambda function.
  8. The Lambda function checks if JWT authentication and authorization is enabled for the OpenSearch Service domain with the respective public key of the Amazon Cognito user pool. If not, it will enable and configure this feature for the OpenSearch Service domain. The Lambda function forwards the query and ID token to OpenSearch Service.
  9. OpenSearch Service validates the JWT with Amazon Cognito:
    1. OpenSearch Service verifies user permissions against fine-grained access control based on group membership.
    2. OpenSearch Service returns query results to the client if authorization succeeds.

The following diagram illustrates the request flow.

Request flow diagram showing authentication and search flow between services.

Prerequisites

Before you deploy the solution, make sure you have the following prerequisites:

Deploy solution resources

To deploy the solution resources, we use an AWS CloudFormation template. Launch the AWS CloudFormation template with the following Launch Stack button.

Enter an appropriate stack name. This name is used as a prefix for resources like OpenSearch Service domains and Lambda functions. Keep the default settings, and choose Create.

The stack deployment takes approximately 15–20 minutes. When deployment is complete, the stack status shows as CREATE_COMPLETE.

The outputs for this CloudFormation stack show important information regarding the deployed resources. This information will be referenced throughout different sections of this post.

On the Outputs tab, note the following values:

  • OpenSearchDashboardURL
  • SharedLambdaRoleArn

On the Resources tab, locate the following information:

  • OpenSearchMasterUserSecret: Choose the Physical ID link, then choose Retrieve Secret Value. Note the user name and password required for OpenSearch Service domain login.
  • IngestDataAndCreateBackendRoles: Choose the Physical ID link to open the Lambda function, needed in later steps.
  • UserPool: Choose the Physical ID link to open the Amazon Cognito user pool, needed in later steps.
  • RestAPI: Choose the Physical ID link to open the API Gateway endpoint, needed in later sections.

AWS CloudFormation Resources tab showing a list of deployed resources in a stack. The tab displays columns for Logical ID, Physical ID, Type, and Status of each resource. This view helps track and manage infrastructure components created by the CloudFormation template.

AWS CloudFormation Outputs tab displaying exported values and information from the stack. The tab shows a table with columns for Output Key, Output Value, and Description. This view allows users to see and access important configuration values and endpoints created by the stack.

In a separate browser tab, log in to the OpenSearch dashboard using OpenSearchDashboardsURL and user credentials noted previously.

Assign permissions to the IAM role associated with the Lambda function

Complete the following steps to map your IAM role to both the all_access and security_manager roles in OpenSearch Service:

  1. In OpenSearch Dashboards, choose Security in the navigation pane, then choose Roles.
  2. Open the all_access role.
  3. In the Mapped users section, choose Manage mapping.
  4. For Backend role, enter the IAM role Amazon Resource name (ARN). This is the value you copied from the CloudFormation stack output for SharedLambdaRoleArn.
  5. Choose Map to confirm.

Interface showing mapping of users to all_access OpenSearch Service role

  1. On the Roles page, open the security_manager role.
  2. In the Mapped users section, choose Manage mapping.
  3. For Backend role, enter the same IAM role ARN.
  4. Choose Map to confirm the changes.

Interface showing mapping of users to security_manager OpenSearch Service role

These steps ensure the IAM role attached to the Lambda function has the necessary permissions to ingest data (all_access) and create roles (security_manager) within the OpenSearch Service domain.

In this sample setup, the Lambda function handles bulk ingestion and role creation without granting any direct access to users, and all_access is provided to the Lambda role solely to enable ingestion. FGAC in OpenSearch provides in-depth access control, allowing you to further tighten the Lambda role permissions by granting only the necessary CRUD operations, rather than full access for ingestion. For more details, refer to Defining users and roles and Fine-grained access control in OpenSearch.

Run the Lambda function to ingest data into the OpenSearch Service domain

On the CloudFormation stack’s Resources tab, locate the IngestDataAndCreateBackendRoles Lambda function. Open the Lambda function, choose Test, and execute it. You can confirm the function’s successful execution by checking Amazon CloudWatch Logs.

This Lambda function is designed to perform bulk ingestion and role creation in the OpenSearch Service domain. It ingests sample clinical research data into OpenSearch Service, creating two indexes (pubmed and clinical_trials), and sets up required OpenSearch Service roles. We explore these roles in detail in the next section.

Map roles and users in OpenSearch Service

In this step, we define two key OpenSearch Service roles:

  • pubmed-admin – Grants full read access to the PubMed index containing biomedical literature and research abstracts, intended for senior research groups
  • pubmed-limited – Provides restricted read access to only specific fields (journal, title, and abstract, where journal is a masked field), intended for researchers with limited data access

We have already created these roles by running the Lambda function in the previous section. The following code is the pubmed-admin OpenSearch Service role description:

The following code is the pubmed-limited OpenSearch Service role description:

The pubmed-admin and pubmed-limited roles serve different purposes, and their main distinction lies in how they control data visibility. Document-level security (DLS) lets you restrict a role to a subset of documents in an index, while field-level security (FLS) lets you control which document fields a user can see. The limited role is configured with FLS to expose only the journal, title, and abstract fields, while masked fields anonymize sensitive data such as journal. On top of these, you can apply DLS to hide specific records, for example, to prevent users from viewing documents from certain journals or publication years. In your use cases, use DLS and FLS to control document and field visibility for different users. These roles are fully configurable; you can add, remove, or update document and field access at any time to match evolving security or business requirements.

To enforce access control, users need to be mapped to appropriate OpenSearch Service roles on OpenSearch Dashboards. Complete the following steps to map users to the OpenSearch Service roles:

  1. On OpenSearch Dashboards, choose Security in the navigation pane, then choose Roles.
  2. Open the pubmed-admin role.
  3. In the Mapped users section, choose Manage mapping.
  4. For Backend role, enter pubmed_admin_group.
  5. Choose Map to confirm the mapping.

Interface showing mapping of users to pubmed-admin OpenSearch Service role

  1. On the Roles page, open the pubmed-limited role.
  2. In the Mapped users section, choose Manage mapping.
  3. For Backend role, enter pubmed_limited_group.
  4. Choose Map to confirm the mapping.

Interface showing mapping of users to pubmed-limited OpenSearch Service role

Backend roles simplify access management in OpenSearch Service. Instead of mapping individual users to OpenSearch service roles, you can map roles to backend roles that users share. This approach lets you map IdP groups directly to the OpenSearch service roles. OpenSearch Service provides options when configuring your OpenSearch Service domain to map JWT claims to OpenSearch Service roles using the roles key.

In this solution, the JWT contains a field called cognito:groups that will be mapped as the roles key. In every JWT, this field has a value for the appropriate group the user belongs to. Based on the field value in the JWT and the mapping defined in the previous step for different research groups, OpenSearch Service domain dynamically assigns permissions:

  • If the JWT contains “cognito:groups”: [“pubmed_admin_group”], the user is granted pubmed_admin access
  • If the JWT contains “cognito:groups”: [“pubmed_limited_group”], the user is granted pubmed_limited access

Take a look at the examples below to understand what a JWT header and payload look like.

Sample JWT header:

{ "kid": "ksBAnCwgFgjaSVlETXx/xeUtvuPkZkacu10Xexample=", "alg": "RS256" }

Sample JWT payload:

{
    "at_hash": "Q7Bljd1Hj4bvC40example",
    "sub": "246894e8-a081-70ab-8fc0-25729example",
    "cognito:groups": [
        "pubmed_limited_group"
    ],
    "email_verified": true,
    "iss": "https://cognito-idp.us-east-1.amazonaws.com/us-east-1_B2example",
    "cognito:username": "PubMedAdminUser",
    "origin_jti": "096e366f-ce11-40e8-9e82-c4a15example",
    "aud": "q72b4a6o3sc2am2c235cqi2vc",
    "event_id": "0545ea01-3026-4563-8d1c-05a07example",
    "token_use": "id",
    "auth_time": 1739269731,
    "exp": 1739273331,
    "iat": 1739269731,
    "jti": "b39d6a3f-1670-4aaa-840a-1a92fexample",
    "email": "[email protected]“
}

Create users in Amazon Cognito

In this section, we create the following Amazon Cognito users:

PubMedAdminUser
PubMedLimitedUser
ClinicalTrialsAdminUser
ClinicalTrialsLimitedUser
ResearchBasicUser

The email address required for each user should be unique. If your email domain supports email alias, you can add a suffix to your own email address by using [email protected]. The following screenshot shows our users.

screenshot of Users section of Cognito User pool showing the target state after all the users are created.

On the CloudFormation stack’s Resources tab, locate the UserPool Amazon Cognito user pool that you noted earlier. Open the user pool in a new browser tab.

To create the Amazon Cognito users, complete the following steps for each user:

  1. On the Amazon Cognito console, choose Users in the navigation pane.
  2. Choose Create user.
  3. For Alias attributes used to sign in, select Email.
  4. For User name, enter a unique user name.
  5. For Email address, enter a unique email address for each user.
  6. Select Mark email address as verified.
  7. Choose Create User.

screenshot of Information to be provided for creating each of the user

Create groups in Amazon Cognito

We create the following groups in Amazon Cognito:

pubmed_admin_group
pubmed_limited_group
clinical_trials_admin_group
clinical_trials_limited_group
research_basic_group

The following screenshot shows created groups.

screenshot of Groups section of Cognito User pool showing the target state after all the groups are created.

To create the Amazon Cognito groups, complete the following steps for each group:

  1. On the Amazon Cognito console, choose Groups in the navigation pane.
  2. Choose Create group.
  3. For Group name, enter a unique name.
  4. Choose Create group.

Add Amazon Cognito users to groups

The users should be added to the groups as follows:

  • Add PubMedAdminUser to the pubmed_admin_group group
  • Add PubMedLimitedUser to the pubmed_limited_group group
  • Add ClinicalTrialsAdminUser to the clinical_trials_admin_group group
  • Add ClinicalTrialsLimitedUser to the clinical_trials_limited_group group
  • Add ResearchBasicUser to the research_basic_group group

To add users to their respective group, complete the following steps for each group:

  1. On the Amazon Cognito console, choose Groups in the navigation pane.
  2. Choose the group to which you want to add a user.
  3. Choose Add user to group.
  4. Choose the user and choose Add.

Log in to generate a JWT

Before running the test queries in the next section, you must obtain the id_token (JWT) for the specified users. The tokens will expire in 60 minutes. If the token is expired for a user, you must log in again to get a fresh token. To log in with your user to get the id_token, complete the following steps:

  1. On the Amazon Cognito console, open your user pool.
  2. Choose App clients in the navigation pane.
  3. Choose the app client.
  4. Choose View login page.

screenshot of the App clients section of the userpool

  1. Enter the user name that you used when creating the user.
  2. Enter the temporary password that you set when creating the user.
  3. For first-time logins, you will be prompted to create a new password. Enter a new password that meets the following requirements:
    1. At least 8 characters
    2. Contains uppercase and lowercase letters
    3. Contains at least one number
    4. Contains at least one special character
  4. Copy the id_token value you generated (without quotation marks).

Query data in OpenSearch Service

This example demonstrates how OpenSearch Service filters search results based on user permissions. We test searches using JWTs for two different users to verify access controls. Each user’s search results are limited to the indexes and documents allowed by their assigned roles.

On the CloudFormation stack’s Resources tab, locate the RestAPI value that you noted earlier. Open the API gateway in a new browser tab.

Complete the following steps to test the search API for each of the scenarios mentioned in this section:

  1. On the API Gateway console, choose Resources in the navigation pane.
  2. Choose the /search resource.
  3. Choose the POST method.
  4. Choose Test.

Screenshot of the Test section for the search API in Amazon API Gateway.

When submitting queries to OpenSearch Service, make sure all double quotation marks are escaped to prevent syntax errors. Additionally, make sure you complete your query before your JWT expires, or you will need to generate a new token. If you attempt to use an expired token, it will result in an error.

For Scenarios 1 and 2, log in with your PubMedAdmin user, and for Scenarios 3 and 4, log in with your PubMedLimitedUser to obtain the required id_token.

Scenario 1

In this first query, we query the pubmed index with the credentials of user PubMedAdminUser, which is part of pubmed_admin_group:

{
  "query": {
    "match_all": {}
  }
}

Add the following values to the respective input fields:

  • For Query strings, enter query="{\"query\":{\"match_all\":{}}}"&index=pubmed
  • For Headers, enter id_token:<id-token-for-PubMedAdminUser>

values to be used for testing scenario 1

The following screenshot shows our query results.

Result of the search API call made for scenario 1

Users with the pubmed_admin role have full access to the PubMed index and can perform unrestricted searches across all fields and document types. This query successfully returns documents with the HTTP 200 status code because the user has complete read permissions on this index.

Scenario 2

Next, we query the clinical-trials index with the credentials of user PubMedAdminUser, who is part of pubmed_admin_group:

{
  "query": {
    "match_all": {}
  }
}

Add the following values to the respective input fields:

  • For Query strings, enter query="{\"query\":{\"match_all\":{}}}"&index=clinical-trials
  • For Headers, enter id_token:<id-token-for-PubMedAdminUser>

values to be used for testing scenario 2

The following screenshot shows our query results.

Result of the search API call made for scenario 2

Despite having admin privileges for PubMed data, this user receives a 403 Forbidden response when attempting to access the clinical-trials index. The error message indicates the lack of necessary permissions for performing search operations on this index.

Scenario 3

Now we query allowed fields in the pubmed index with the credentials of user PubMedLimitedUser, which is part of pubmed_limited_group:

{
    "query": {
        "match": {
            "title": "molecular biology"
        }
    }
}

Add the following values to the respective input fields:

  • For Query strings, enter query="{\"query\":{\"match\":{\"title\": \"molecular biology\"}}}"&index=pubmed
  • For Headers, enter id_token:<id-token-for-PubMedLimitedUser>

values to be used for testing scenario 3

The following screenshot shows our query results.

Result of the search API call made for scenario 3

Users with the pubmed_limited role can successfully query specific fields like title, but with restricted access to sensitive information. The query returns results with the HTTP 200 status code, but the journal field is anonymized due to field-level security policies. Users can search and view certain fields while having sensitive data automatically masked or excluded from their results.

Scenario 4

Lastly, we query unauthorized fields in the pubmed index with the credentials of user PubMedLimitedUser, which is part of pubmed_limited_group:

{
    "query": {
        "match": {
            "research_group": "RG_345"
        }
    }
}

Add the following values to the respective input fields:

  • For Query strings, enter query="{\"query\":{\"match\":{\"research_group\":\"RG_345\"}}}"&index=pubmed
  • For Headers, enter id_token:<id-token-for-PubMedLimitedUser>

values to be used for testing scenario 4

The following screenshot shows our query results.

Result of the search API call made for scenario 4

When a user with the pubmed_limited role attempts to query the restricted research_group field, OpenSearch returns a successful response (HTTP 200) but with empty results. This behavior occurs because field-level security is enforcing access controls instead of returning a HTTP 403 error, it silently filters out the restricted field from both the query and results. This security-by-obscurity approach means that users can’t determine whether their query failed due to lack of permissions or genuine absence of matching documents.

Clean up

To avoid incurring further AWS usage charges, delete the resources created in this post by deleting the CloudFormation stack. This step will remove all resources except Lambda layers. To delete the Lambda layers, navigate to the Layers page on the Lambda console, and delete the layers named <CloudFormation-Stack-Name>-requests and <CloudFormation-Stack-Name>-crypt.

Conclusion

In this post, we discussed how JWTs provide a robust and scalable authentication mechanism that can be integrated with existing IdPs. We also demonstrated how to seamlessly integrate fine-grained access control across search applications. Organizations can define granular permissions within their IdP, making sure sensitive information remains protected. The JWT integration with OpenSearch Service enables secure, efficient access control, so users can only access role-appropriate information while simplifying compliance and access management.

If you have feedback about this post, leave them in the comments section. If you have questions about this post, start a new thread on AWS Security, Identity, and Compliance re:Post or contact AWS Support.


About the authors

Ramya Bhat is a Data Analytics Consultant at AWS, specializing in the design and implementation of cloud-based data platforms. She builds enterprise-grade solutions across search, data warehousing, and ETL that enable organizations to modernize data ecosystems and derive insights through scalable analytics. She has delivered customer engagements across healthcare, insurance, fintech, and media sectors.

Shubhansu Sawaria is a Sr. Delivery Consultant – SRC at AWS, based in Bangalore, India. He specializes in designing and implementing comprehensive AWS Cloud security solutions. He has developed security solutions for startups, banks, and healthcare organizations. His expertise helps organizations elevate their cloud security infrastructures, achieve compliance objectives, and provide robust data protection.

Soujanya Konka is a Sr. Solutions Architect and Analytics Specialist at AWS, focused on helping customers build their ideas in the cloud. She has expertise in designing and implementing enterprise search solutions and advanced data analytics at scale.

How AppZen enhances operational efficiency, scalability, and security with Amazon OpenSearch Serverless

Post Syndicated from Prashanth Dudipala, Madhuri Andhale original https://aws.amazon.com/blogs/big-data/how-appzen-enhances-operational-efficiency-scalability-and-security-with-amazon-opensearch-serverless/

AppZen is a leading provider of AI-driven finance automation solutions. The company’s core offering centers around an innovative AI platform designed for modern finance teams, featuring expense management, fraud detection, and autonomous accounts payable solutions. AppZen’s technology stack uses computer vision, deep learning, and natural language processing (NLP) to automate financial processes and ensure compliance. With this comprehensive solution approach, AppZen has a well-established enterprise customer base that includes one-third of the Fortune 500 companies.

AppZen hosts all its workloads and application infrastructure on Amazon Web Services (AWS), continuously modernizing its technology stack to effectively operationalize and host its applications. Centralized logging, a critical component of this infrastructure, is essential for monitoring and managing operations across AppZen’s diverse workloads. As the company experienced rapid growth, the legacy logging solution struggled to keep pace with expanding needs. Consequently, modernizing this system became one of AppZen’s top priorities, prompting a comprehensive overhaul to enhance operational efficiency and scalability.

In this blog we show, how AppZen modernizes its central log analytics solution from Elasticsearch to Amazon OpenSearch Serverless providing an optimized architecture to meet above mentioned requirements.

Challenges with the legacy logging solution

With a growing number of business applications and workloads, AppZen had an increasing need for comprehensive operational analytics using log data across its multi-account organization in AWS Organizations. AppZen’s legacy logging solution created several key challenges. It lacked the flexibility and scalability to efficiently index and make the logs available for real-time analysis, which was crucial for tracking anomalies, optimizing workloads, and ensuring efficient operations.

The legacy logging solution consisted of a 70-node Elasticsearch cluster (with 30 hot nodes and 40 warm nodes), it struggled to keep up with the growing volume of log data as AppZen’s customer base expanded and new mission-critical workloads were added. This led to performance issues and increased operational complexity. Maintaining and managing the self-hosted Elasticsearch cluster required frequent software updates and infrastructure patching, resulting in system downtime, data loss, and added operational overhead for the AppZen CloudOps team.

Migrating the data to a patched node cluster took 7 days, far exceeding industry standard and AppZen’s operational requirements. This extended downtime introduced data integrity risk and directly impacted the operational availability of the centralized logging system crucial for teams to troubleshoot across critical workloads. The system also suffered frequent data loss that impacted real-time metrics monitoring, dashboarding, and alerting because its application log-collecting agent Fluent Bit lacked essential features such as backoff and retry.

AppZen has an NGINX proxy instance controlling authorized user access to data hosted on Elasticsearch. Upgrades and patching of the instance introduced frequent system downtimes. All user requests are routed through this proxy layer, where the user’s permission boundary is evaluated. This had an added operations overhead for administrators to manage users and group mapping at the proxy layer.

Solution overview

AppZen re-platformed its central log analytics solution with Amazon OpenSearch Serverless and Amazon OpenSearch Ingestion. Amazon OpenSearch Serverless lets you run OpenSearch in the AWS Cloud, so you can run large workloads without configuring, managing, and scaling OpenSearch clusters. You can ingest, analyze, and visualize your time-series data without infrastructure provisioning. OpenSearch Ingestion is a fully managed data collector that simplifies data processing with built-in capabilities to filter, transform, and enrich your logs before analysis.

This new serverless architecture, shown in the following architecture diagram, is cost-optimized, secure, high-performing, and designed to scale efficiently for future business needs. It serves the following use cases:

  • Centrally monitor business operations and data analysis for deep insights
  • Application monitoring and infrastructure troubleshooting

Together, OpenSearch Ingestion and OpenSearch Serverless provide a serverless infrastructure capable of running large workloads without configuring, managing, and scaling the cluster. It provides data resilience with persistent buffers that can support the current 2 TB per day pipeline data ingestion requirement. IAM Identity Center support for OpenSearch Serverless helped manage users and their access centrally eliminating a need for NGINX proxy layer.

The architecture diagram also shows how separate ingestion pipelines were deployed. This configuration option improves deployment flexibility based on the workload’s throughput and latency requirements. In this architecture, Flow-1 is a push-based data source (such as HTTP and OTel logs) where the workload’s Fluent Bit DaemonSet is configured to ingest log messages into the OpenSearch Ingestion pipeline. These messages are retained in the pipeline’s persistent buffer to provide data durability. After processing the message, it’s inserted into OpenSearch Serverless.

And Flow-2 is a pull-based data source such as Amazon Simple Storage Service (Amazon S3) for OpenSearch Ingestion where the workload’s Fluent Bit DaemonSets are configured to sync data to an S3 bucket. Using S3 Event Notifications, the new log records creation notifications are sent to Amazon Simple Queue Service (Amazon SQS). OpenSearch Ingestion consumes this notification and processes the record to insert into OpenSearch Serverless, delegating the data durability to the data source. For both Flow-1 and Flow-2, the OpenSearch Ingestion pipelines are configured with a dead-letter queue to record failed ingestion messages to the S3 source, making them accessible for further analysis.

AWS logging architecture with ingestion flows to OpenSearch Serverless

For service log analytics, AppZen adopted a pull-based approach as shown in the following figure, where all service logs published to Amazon CloudWatch are migrated an S3 bucket for further processing. An AWS Lambda processor is triggered when every new message is ingested to the S3 bucket, and the processed message is then uploaded to the S3 bucket for OpenSearch ingestion. The following diagram shows the OpenSearch Serverless architecture for the service log analytics pipeline.

A log ingestion architecture for service log analytics

Workloads and infrastructure spread across multiple AWS accounts can securely send logs to the central log analytics platform over a private network using virtual private cloud (VPC) peering and AWS PrivateLink endpoints, as shown in the following figure. Both OpenSearch Ingestion and OpenSearch Serverless are provisioned in the same account and Region, with cross-account ingestion enabled for workloads in other member accounts of the AWS Organizations account.

Cross-account AWS logging with secure centralized collection

Migration approach

The migration to OpenSearch Serverless and OpenSearch Ingestion involved performance evaluation and fine-tuning the configuration of the logging stack, followed by migration of production traffic to new platform. The first step was to configure and benchmark the infrastructure for cost-optimized performance.

Parallel ingestion to benchmark OCU capacity requirements

OpenSearch Ingestion scales elastically to meet throughput requirements during workload spikes. Enabling persistent buffering on ingestion pipelines with push-based data sources provided data durability and reliability. Data ingestion pipelines are ingesting at a rate of 2 TB per day. Due to AppZen’s 90-day data retention requirement around its ingested data, at any time, there is approximately 200 TB of indexed historical data stored in the OpenSearch Serverless cluster. To evaluate performance and costs before deploying to production, data sources were configured to ingest data in parallel into the new OpenSearch Serverless environment along with an existing setup already running in production with Elasticsearch.

To achieve parallel ingestion, AppZen installed another Fluent Bit DaemonSet configured to ingest into the new pipeline. This was for two reasons: 1) To avoid interruption due to changes to existing ingestion flow and 2) New workflows are much more straightforward when the data preprocessing step is offloaded to OpenSearch Ingestion, eliminating the need for custom lua script use in Fluent Bit.

Pipeline configuration

The production pipeline configuration was implemented with different strategies based on data source types. Push-based data sources were configured with persistent buffer enabled for data durability and a minimum of three OpenSearch Compute Units (OCUs) to provide high availability across three Availability Zones. In contrast, pull-based data sources, which used Amazon S3 as their source, didn’t require persistent buffering due to the inherent durability features of Amazon S3. Both pipeline types were initially configured with a minimum of three OCUs and a maximum of 50 OCUs to establish baseline performance metrics. This setup meant the team could monitor and analyze actual workload patterns, and therefore fine-tune worker configurations for optimal OCU usage. Through continuous monitoring and adjustment, the pipeline configurations were changed and optimized to efficiently handle both daily average loads and peak traffic periods, providing cost-effective and reliable data processing operations.

For AppZen’s throughput requirement, in the pull-based approach, they identified six Amazon S3 workers in the OpenSearch Ingestion pipelines optimally processing 1 OCU at 80% efficiency. Following the best practices recommendation, at this system.cpu.usage.value metrics threshold, the pipeline was configured to auto scale. With each worker capable of processing 10 messages, AppZen identified cost-optimized configuration of 50 OCUs as maximum OCU configuration for its pipelines that is capable of processing up to 3,000 messages in parallel. This pipeline configuration shown below supports its peak throughput requirements

# This is an OpenSearch Ingestion - pipeline configuration for processing Kubernetes logs and sending them to OpenSearch Serverless
# Data Flow: S3 -> SQS -> OpenSearch Ingestion -> OpenSearch + S3 Archive
# index_name here is kubernetes.namespace_name or k8 service name
# If k8 Index name is dev: Service1-dev
# If k8 Index name is non-dev: Service1-allenv
version: "2"
entry-pipeline:
  # Source (S3 + SQS)
  # Reads logs from S3 bucket via SQS notifications
  # 6 workers process JSON files. Deletes S3 objects after processing
  source:
    s3:
      workers: 6
      notification_type: "sqs"
      codec:
        ndjson:
      compression: "none"
      aws:
        region: "us-east-1"
        sts_role_arn: "<roleArn>"
      acknowledgments: true
      delete_s3_objects_on_read: true
      sqs:
        queue_url: "https://sqs.us-east-1.amazonaws.com/********1234/us-s3-k8-log"
        visibility_duplication_protection: true
  # Processing Pipeline
  # Timestamp: Adds @timestamp from ingestion time
  # Index naming: Sets index_name from Kubernetes namespace
  processor:
    - date:
        from_time_received: true
        destination: "@timestamp"
    - add_entries:
        entries:
        - key: "index_name"
          value_expression: "/kubernetes_namespace/name"
          add_when: "/index_name == null"
    - delete_entries:
        with_keys: [ "tmp" ]
    
    # JSON parsing: Parses nested JSON in log and message fields
    # Failed JSON parsing skipped silently
    - parse_json:
        source: /log
        handle_failed_events: 'skip_silently'
    - parse_json:
        source: /message
        handle_failed_events: 'skip_silently'
    
    # Environment detection: Uses grok patterns to extract environment from namespace names
    - grok:
        grok_when: 'contains(/index_name, "prod-") or contains(/index_name, "prod-k1-") or contains(/index_name, " prod-k2-")'
        match:
          index_name:
            - '%{WORD:prefix}-%{GREEDYDATA:suffix}-%{INT:ignore}'
            - '%{WORD:prefix}-%{GREEDYDATA:suffix}'
    - add_entries:
        entries:
        - key: "/suffix"
          value_expression: "/index_name"
          add_when: "/suffix == null"
        - key: "/labels/environment"
          value_expression: "/prefix"
          add_when: "/prefix != null"
          overwrite_if_key_exists: true
        - key: "/labels/environment"
          value_expression: "/labels_environment"
          add_when: "/labels_environment != null"
          overwrite_if_key_exists: true
  # Routing Logic 
  # k8: Normal Kubernetes logs
  # k8-debug: DEBUG level logs (separate retention)
  # unknown: Logs without proper metadata
  routes:
    - k8: '/kubernetes_namespace/name != null or /data_source == "kubernetes"'
    - k8-debug: '/data_source == "kubernetes" and /levelname == "DEBUG"'
    - unknown: '/kubernetes_namespace/name == null and /suffix == null and /log_group == null'
  # Sinks (3 destinations)
  # S3 Archive: All logs stored in S3 with date partitioning
  # OpenSearch (Normal): ${suffix}-v4-k8 index for regular logs
  # OpenSearch (Debug): ${suffix}-v4-k8-debug index for debug logs
  sink:
    - s3:
        aws:
          region: "us-east-1"
          sts_role_arn: "<roleArn>"
        bucket: <logS3Bucket>
        object_key:
          path_prefix: 'us/${getMetadata("s3-prefix")}/%{yyyy}/%{MM}/%{dd}/'
        codec:
          json:
        compression: "none"
        threshold:
          maximum_size: 20mb
          event_collect_timeout: PT10M
    - opensearch:
        hosts: ["https://<AossDomainUrl>"]
        index: "${/suffix}-v4-k8"
        index_type: custom
        # Max 15 retries for OpenSearch operations
        max_retries: 15
        aws:
          # IAM role that the pipeline assumes to access the domain sink
          sts_role_arn: "<roleArn>"
          region: "us-east-1"
          serverless: true
          serverless_options:
            network_policy_name: "prod-logging-network"
        # Error Handling:
        # Dead Letter Queue (DLQ) to S3 for failed OpenSearch writes
        dlq:
          s3:
            bucket: "<dlqS3Bucket>"
            key_path_prefix: "/k8/"
            region: "us-east-1"
            sts_role_arn: "<roleArn>"
        routes:
          - k8
    - opensearch:
        hosts: ["https://<AossDomainUrl>"]
        index: "${/suffix}-v4-k8-debug"
        index_type: custom
        max_retries: 15
        aws:
          # IAM role that the pipeline assumes to access the domain sink
          sts_role_arn: "<roleArn>"
          region: "us-east-1"
          serverless: true
          serverless_options:
            network_policy_name: "prod-logging-network"
        dlq:
          s3:
            bucket: "<dlqS3Bucket>"
            key_path_prefix: "/k8-debug/"
            region: "us-east-1"
            sts_role_arn: "<roleArn>"
        routes:
          - k8-debug
    - opensearch:
        hosts: ["https://<AossDomainUrl>"]
        index: "unknown"
        index_type: custom
        max_retries: 15
        aws:
          # IAM role that the pipeline assumes to access the domain sink
          sts_role_arn: "<roleArn>"
          region: "us-east-1"
          serverless: true
          serverless_options:
            network_policy_name: "prod-logging-network"
        dlq:
          s3:
            bucket: "<dlqS3Bucket>"
            key_path_prefix: "/unknown/"
            region: "us-east-1"
            sts_role_arn: "<roleArn>"
        routes:
          - unknown

Indexing strategy

When working with search engine, understanding index and shard management is crucial. Indexes and their corresponding shards consume memory and CPU resources to maintain metadata. A key challenge emerges when having numerous small shards in a system because it leads to higher resource consumption and operational overhead. In the traditional approach, you typically create indices at the microservice level for each environment (prod, qa, and dev). For example, indices would be named like prod-k1-service or prod-k2-service, where k1 and k2 represent different microservices. With hundreds of services and daily index rotation, this approach results in thousands of indices, making management complex and resource intensive. When implementing OpenSearch Serverless, you should adopt a consolidated indexing strategy that moves away from microservice-level index creation. Rather than creating individual indices like prod-k1-service and prod-k2-service for each microservice and environment, you should consolidate the data into broader environment-based indices such as prod-service, which contains all service data for the production environment. This consolidation is essential because OpenSearch Serverless scales based on resources and has specific limitations on the number of shards per OCU. This means that having a higher number of small shards will lead to higher OCU consumption.

However, although this consolidated approach can significantly reduce operational costs and simplify management through built-in data lifecycle policies, it presents a notable challenge for multi-tenant scenarios. Organizations with strict security requirements, where different teams need access to specific indices only, might find this consolidated approach challenging to implement. For such cases, a more granular indices approach might be necessary to maintain proper access control, even though it can result in higher resource consumption.

By carefully evaluating your security requirements and access control needs, you can choose between a consolidated approach for optimized resource utilization or a more granular approach that better supports fine-grained access control. Both approaches are supported in OpenSearch Serverless, so you can balance resource optimization with security requirements based on your specific use case.

Cost optimization

OpenSearch Ingestion allocates some OCUs from configured pipeline capacity for persistent buffering, which provides data durability. While monitoring, AppZen observed higher OCU usage for this persistent buffer when processing high-throughput workloads. To optimize this capacity configuration, AppZen decided to classify its workloads into push-based and pull-based categories depending on their throughput and latency requirements. Achieving this created new parallel pipelines to operate these flows in parallel, as shown in the architecture diagram earlier in the post. Fluent Bit agent collector configurations were accordingly modified based on the workload classification.

Depending on the cost and performance requirements for the workload, AppZen adopted the appropriate ingestion flow. For low latency and low-throughput workload requirements, AppZen chose the push-based approach. For high-throughput workload requirements, AppZen adopted the pull-based approach, which helped lower the persistent buffer OCU usage by relying on durability to the data source. In the pull-based approach, AppZen further optimized on the storage cost by configuring the pipeline to automatically delete the processed data from the S3 bucket after successful ingestion

Monitoring and dashboard

One of the key design principles for operational excellence in the cloud is to implement observability for actionable insights. This helps gain a comprehensive understanding of the workloads to help improve performance, reliability, and the cost involved. Both OpenSearch Serverless and OpenSearch Ingestion publish all metrics and logs data to Amazon CloudWatch. After identifying key operational OpenSearch Serverless metrics and OpenSearch Service pipeline metrics, AppZen set up CloudWatch alarms to send a notification when certain defined thresholds are met. The following screenshot shows the number of OCUs used to index and search collection data.

OpenSearch Serverless capacity management dashboard showing OCU usage graphs

The following screenshot shows the number of Ingestion OCUs in use by the pipeline.

The following screenshot shows the percentage of available CPU usage for OCU.

The following screenshot shows the percent usage of buffer based on the number of records in the buffer.

Conclusion

AppZen successfully modernized their logging infrastructure by migrating to a serverless architecture using Amazon OpenSearch Serverless and OpenSearch Ingestion. By adopting this new serverless solution, AppZen eliminated an operations overhead that involved 7 days of data migration effort during each quarterly upgrade and patching cycle of Kubernetes cluster hosting Elasticsearch nodes. Also, with the serverless approach, AppZen was able to avoid index mapping conflicts by using index templates and a new indexing strategy. This helped the team save an average 5.2 hours per week of operational effort and instead use the time to focus on other priority business challenges. AppZen achieved a better security posture through centralized access controls with OpenSearch Serverless, eliminating the overhead of managing a duplicate set of user permissions at the proxy layer. The new solution helped AppZen handle growing data volume and build real-time operational analytics while optimizing cost, improving scalability and resiliency. AppZen optimized costs and performance by classifying workloads into push-based and pull-based flows, so they could choose the appropriate ingestion approach based on latency and throughput requirements.

With this modernized logging solution, AppZen is well positioned to efficiently monitor their business operations, perform in-depth data analysis, and effectively monitor and troubleshooting the application as they continue to grow. Looking ahead, AppZen plans to use OpenSearch Serverless as a vector database, incorporating Amazon S3 Vectors, generative AI, and foundation models (FMs) to enhance operational tasks using natural language processing.

To implement a similar logging solution for your organization, begin by exploring AWS documentation on migrating to Amazon OpenSearch Serverless and setting up OpenSearch Serverless. For guidance on creating ingestion pipelines, refer to the AWS guide on OpenSearch Ingestion to begin modernizing your logging infrastructure.


About the authors

Prashanth Dudipala is a DevOps Architect at AppZen, where he helps build scalable, secure, and automated cloud platforms on AWS. He’s passionate about simplifying complex systems, enabling teams to move faster, and sharing practical insights with the cloud community.

Madhuri Andhale is a DevOps Engineer at AppZen, focused on building and optimizing cloud-native infrastructure. She is passionate about managing efficient CI/CD pipelines, streamlining infrastructure and deployments, modernizing systems, and enabling development teams to deliver faster and more reliably. Outside of work, Madhuri enjoys exploring emerging technologies, traveling to new places, experimenting with new recipes, and finding creative ways to solve everyday challenges.

Manoj Gupta is a Senior Solutions Architect at AWS, based in San Francisco. With over 4 years of experience at AWS, he works closely with customers like AppZen to build optimized cloud architectures. His primary focus areas are Data, AI/ML, and Security, helping organizations modernize their technology stacks. Outside of work, he enjoys outdoor activities and traveling with family.

Prashant Agrawal is a Sr. Search Specialist Solutions Architect with Amazon OpenSearch Service. He works closely with customers to help them migrate their workloads to the cloud and helps existing customers fine-tune their clusters to achieve better performance and save on cost. Before joining AWS, he helped various customers use OpenSearch and Elasticsearch for their search and log analytics use cases. When not working, you can find him traveling and exploring new places. In short, he likes doing Eat → Travel → Repeat.

AWS Weekly Roundup: Amazon Aurora 10th anniversary, Amazon EC2 R8 instances, Amazon Bedrock and more (August 25, 2025)

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-aurora-10th-anniversary-amazon-ec2-r8-instances-amazon-bedrock-and-more-august-25-2025/

As I was preparing for this week’s roundup, I couldn’t help but reflect on how database technology has evolved over the past decade. It’s fascinating to see how architectural decisions made years ago continue to shape the way we build modern applications. This week brings a special milestone that perfectly captures this evolution in cloud database innovation as Amazon Aurora celebrated 10 years of database innovation.

Birthday cake with words Happy Birthday Amazon Aurora!

Amazon Web Services (AWS) Vice President Swami Sivasubramanian reflected on LinkedIn about his journey with Amazon Aurora, calling it “one of the most interesting products” he’s worked on. When Aurora launched in 2015, it shifted the database landscape by separating compute and storage. Now trusted by hundreds of thousands of customers across industries, Aurora has grown from a MySQL-compatible database to a comprehensive platform featuring innovations such as Aurora DSQL, serverless capabilities, I/O-Optimized pricing, zero-ETL integrations, and generative AI support. Last week’s celebration on August 21 highlighted this decade-long transformation that continues to simplify database scaling for customers.

Last week’s launches

In addition to the inspiring celebrations, here are some AWS launches that caught my attention:

  • AWS Billing and Cost Management introduces customizable Dashboards — This new feature consolidates cost data into visual dashboards with multiple widget types and visualization options, combining information from Cost Explorer, Savings Plans, and Reserved Instance reports to help organizations track spending patterns and share standardized cost reporting across accounts.
  • Amazon Bedrock simplifies access to OpenAI open weight models — AWS has streamlined access to OpenAI’s open weight models (gpt-oss-120b and gpt-oss-20b), making them automatically available to all users without manual activation while maintaining administrator control through IAM policies and service control policies.
  • Amazon Bedrock adds batch inference support for Claude Sonnet 4 and GPT-OSS models —This feature provides asynchronous processing of multiple inference requests with 50 percent lower pricing compared to on-demand inference, optimizing high-volume AI tasks such as document analysis, content generation, and data extraction with Amazon CloudWatch metrics for tracking batch workload progress
  • AWS launching Amazon EC2 R8i and R8i-flex memory-optimized instances — Powered by custom Intel Xeon 6 processors, these new instances deliver up to 20 percent better performance and 2.5 times higher memory throughput than R7i instances, making them ideal for memory-intensive workloads like databases and big data analytics, with R8i-flex offering additional cost savings for applications that don’t fully utilize compute resources.
  • Amazon S3 introduces batch data verification feature — A new capability in S3 Batch Operations that offers efficient verification of billions of objects using multiple checksum algorithms without downloading or restoring data, generating detailed integrity reports for compliance and audit purposes regardless of storage class or object size.

Other AWS news

Here are some additional projects and blog posts that you might find interesting:

  • Amazon introduces DeepFleet foundation models for multirobot coordination — Trained on millions of hours of data from Amazon fulfillment and sortation centers, these pioneering models predict future traffic patterns for robot fleets, representing the first foundation models specifically designed for coordinating multiple robots in complex environments.
  • Building Strands Agents with a few lines of code — A new blog demonstrates how to build multi-agent AI systems with a few lines of code, enabling specialized agents to collaborate seamlessly, handle complex workflows, and share information through standardized protocols for creating distributed AI systems beyond individual agent capabilities.
  • AWS Security Incident Response introduces ITSM integrations — New integrations with Jira and ServiceNow provide bidirectional synchronization of security incidents, comments, and attachments, streamlining response while maintaining existing processes, with open source code available on GitHub for customization and extension to additional IT service management (ITSM) platforms.
  • Finding root-causes using a network digital twin graph and agentic AI — A detailed blog post shows how AWS collaborated with NTT DOCOMO to build a network digital twin using graph databases and autonomous AI agents, helping telecom operators to move beyond correlation to identify true root causes of complex network issues, predict future problems, and improve overall service reliability.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS Summits — Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Toronto (September 4), Los Angeles (September 17), and Bogotá (October 9).
  • AWS re:Invent 2025 — This flagship annual conference is coming to Las Vegas from December 1–5. The event catalog is now available. Mark your calendars for this not to be missed gathering of the AWS community.
  • AWS Community Days — Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Adria (September 5), Baltic (September 10), Aotearoa (September 18), South Africa (September 20), Bolivia (September 20), Portugal (September 27).

Join the AWS Builder Center to learn, build, and connect with builders in the AWS community. Browse here for upcoming in-person and virtual developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Betty

Zeta reduces banking incident response time by 80% with Amazon OpenSearch Service observability

Post Syndicated from Deepesh Dhapola original https://aws.amazon.com/blogs/big-data/zeta-reduces-banking-incident-response-time-by-80-with-amazon-opensearch-service-observability/

This is a guest post co-written with Shashidhar Soppin, Manochandra Menni and Anchal Kansal from Zeta.

Zeta is a core banking technology provider that enables banks to rapidly launch extensible banking assets and liability products. Zeta’s primary products are Olympus and Tachyon. Olympus is a platform as a service (PaaS) that simplifies building and operating cloud-native, secure and distributed multi-tenant software as a service (SaaS) products. It blends infrastructure as code and GitOps methodologies for efficient and consistent deployment of SaaS products. Its architecture prioritizes strong tenant isolation, real-time event processing, and comprehensive observability, supporting robust API integrations and seamless deployment. Zeta’s Tachyon is a full-stack, cloud-native, API-first digital-banking SaaS service delivered via Olympus. The banking services of Tachyon include payment engines (for UPI, credit, debit, and prepaid cards), savings & checking account management, etc. Tachyon is a modern debit processing product with personal finance management and card controls. It is designed to increase usage, upsell credit, reduce fraud, and improve customer satisfaction. The Tachyon product offers comprehensive provisioning, payments, and account management APIs and SDKs, enabling seamless integration of financial products into third-party apps without compromising privacy and security. Zeta operates Tachyon as a multi-tenant SaaS product, serving customers who are configured as individual tenants within the system. Zeta’s technology stack is monitored by their Customer Service Navigator product (CSN), which is part of Olympus.

As a global SaaS provider, Zeta needed a solution capable of monitoring tenants, measuring SLAs, meeting local regulatory requirements, and scaling efficiently with both new tenant onboarding and seasonal usage spikes. Zeta sought a cost-effective, scalable system that would provide a unified “single pane of glass” to monitor the application services, cloud infrastructure, open-source components, and third-party products.

Zeta faced a formidable challenge in orchestrating a cohesive monitoring system across a rapidly expanding multi-tenant environment, diverse domains, and numerous tools. As more tenants joined their system, the complexity grew exponentially, making Zeta’s monitoring solution increasingly difficult to maintain. The primary challenge stemmed from fragmented monitoring tools that made it difficult to quickly identify root causes across interconnected systems, leading to prolonged troubleshooting times and potential service degradation. When users reported issues, such as credit card payment problems, Site Reliability Engineering (SRE) team had to navigate through a several disparate monitoring tools and siloed data, and the lack of integrated observability resulted in time-consuming manual correlation efforts. This multi-tenant, multi-solution landscape significantly complicated the ability to maintain consistent monitoring standards and service levels. The challenge was further complicated by the complex regulatory landscape, where global expansion required adherence to diverse local regulations, necessitating a flexible architecture capable of accommodating varying data retention policies and access controls across different jurisdictions. Each new tenant addition multiplied the complexity of balancing the monitoring needs of internal SRE teams and customers, requiring sophisticated data segregation and access management. Additionally, Zeta required comprehensive anomaly detection capabilities across systems, components, infrastructure, and operations, requiring a solution that could scale dynamically while establishing dynamic baselines and identifying subtle patterns that might indicate emerging issues. As the tenant base continued to grow, the need for a unified, scalable monitoring solution that could streamline these processes, enhance operational visibility, and maintain system integrity became critical.

Zeta’s goal was to streamline their processes and enhance operational visibility across the entire technology landscape. By addressing these challenges, Zeta aimed to create a unified observability solution that would significantly improve incident response times, enhance regulatory compliance posture, and ultimately deliver a more reliable and performant service to their global customer base.

In this post we explain how Zeta built a more unified monitoring solution using Amazon OpenSearch Service that improved performance, reduced manual processes, and increased end-user satisfaction. Zeta has achieved over an 80% reduction in mean time to resolution (MTTR), with incident response times decreasing from 30+ minutes to under 5 minutes.

Solution overview

Zeta designed and built an observability system, CSN, to deliver comprehensive visibility across the service environment. CSN is part of the Olympus suite of products. CSN serves as the primary interface for the SRE team, offering real-time service health dashboards, infrastructure monitoring, SLA performance analytics, and an admin panel for user management. The system is equipped with single sign-on (SSO) integration and enforces role-based access control (RBAC) to enable secure, granular access. With CSN, SREs can efficiently monitor system health, receive actionable alerts and warnings, and manage operational workflows across critical services.

CSN is powered by OpenSearch Service to provide an integrated solution for DevOps and Site Reliability Engineers to help identify critical events and issues. Zeta chose OpenSearch Service because it offers a fully managed, open-source search analytics engine that scales effortlessly to handle the increasing number of tenants, associated data growth, and analytics needs. It’s seamless integration with AWS services, robust security features, and support for real-time data ingestion and querying make it ideal for powering the CSN dashboards and analytics workloads. The following diagram illustrates the CSN deployment architecture.

Zeta CSN Deployment Architecture

The OpenSearch Service domain uses the Multi-AZ with Standby deployment model, following AWS best practices for high availability and fault tolerance. Nodes—including dedicated cluster manager nodes, data nodes, and UltraWarm nodes—are distributed evenly across three Availability Zones in the same AWS Region. Availability Zones 1 and 2 handle active indexing and search traffic, and Availability Zone 3 contains standby nodes that remain passive during normal operations. If an Availability Zone failure occurs, OpenSearch Service automatically promotes standby nodes to active status, maintaining cluster operations with minimal disruption and no need for data redistribution.

The OpenSearch cluster consists of three dedicated cluster manager nodes and a multiple-of-three data node count to maintain quorum and balanced shard allocation. Each index uses at least two replicas, providing redundant copies of data across the Availability Zones. This Multi-AZ with Standby configuration delivers high resilience and rapid failover, supporting continuous service availability and robust disaster recovery for the observability workloads.

Data collection and ingestion

The observability strategy centers on a data collection and ingestion pipeline designed to handle the complexity and scale. The architecture, as shown in the following diagram, addresses three critical data types: AWS resource logs, application logs, and distributed traces, with each data type using tailored collection and processing methods optimized for the workloads.

Zeta CSN Data Ingestion

AWS resource logs collection

The infrastructure spans multiple AWS services including Amazon Elastic Kubernetes Service(Amazon EKS), Amazon Relational Database Service(Amazon RDS), Amazon Redshift, Application Load Balancer, Amazon Managed Streaming for Apache Kafka (Amazon MSK), Amazon Elastic Compute Cloud (Amazon EC2) and more. Zeta uses Amazon CloudWatch Logs as the primary collection point for AWS service logs, which provides native integration with these services.

AWS services send their logs directly to CloudWatch Logs, which are then pulled by Fluentd running on the Amazon EKS cluster for centralized processing. This approach natively captures operational data from the AWS resources, including:

  • Database operational logs and audit trails from Amazon RDS instances
  • Data warehouse query execution logs from Amazon Redshift
  • Application Load Balancer access logs capturing traffic patterns and performance metrics
  • Kafka cluster operational logs from Amazon MSK
  • AWS API invocation audit trails from AWS CloudTrail
  • Container runtime and operating system logs from Amazon EC2
  • During the log collection, personally identifiable information (PII) is filtered out. The solution adheres strictly to PCI-DSS guidelines throughout this process.

Zeta used Amazon MSK as a scalable and reliable backbone for collecting and streaming logs from various sources across the AWS resources. Logs are ingested into Amazon MSK, providing a durable and fault-tolerant buffer that decouples log producers from consumers. This architecture enables real-time log streaming and supports advanced processing pipelines before the logs are routed to the OpenSearch Service. By integrating Amazon MSK into the logging workflow, scalability, resilience, and flexibility is improved, so that high log volumes are efficiently managed without impacting downstream systems. This approach, combined with native AWS integrations, minimizes operational complexity and maintains comprehensive, centralized log visibility across the cloud environment.

Fluentd processes these logs and routes them directly to OpenSearch Service, maintaining the benefits of AWS integration while providing centralized accessibility. This centralized logging approach with built-in buffering capabilities reduces the direct load on OpenSearch Service by batching and optimizing log delivery, helping to prevent potential ingestion bottlenecks during high-volume periods. The approach alleviates the need for custom log shipping agents on AWS resources, reducing operational overhead while maintaining comprehensive coverage of the cloud infrastructure.

Application logs processing

For application-level observability, a pipeline using Fluentd is deployed as Kubernetes DaemonSet. Application microservices running on Amazon EKS generate logs that Fluentd DaemonSets collect, parses, and enrich with metadata such as pod names, namespaces, and service identifiers. The processed logs then flow through Amazon MSK for reliable, high-throughput message streaming before final processing by Fluentd and indexing in OpenSearch Service.

This Kafka-based approach provides several advantages:

  • Decoupling – This helps producers and consumers to operate independently, so that Zeta can scale ingestion and processing separately based on demand.
  • Backpressure handling – Using Kafka’s buffering capabilities, this manages traffic spikes during peak banking hours, absorbing sudden increases in log volume while maintaining system stability during seasonal usage surges.
  • Durability of logs – The system maintains logs durably so that no log data is lost during system maintenance or unexpected failures through message persistence.

The logs then pass through a second Fluentd layer for final processing and routing to OpenSearch Service, where they’re indexed across service-specific indexes (app-index, falco-index, kong-index).

Distributed trace collection

To address the challenge of correlating issues across Zeta’s microservices architecture, system uses distributed tracing using Jaeger, an open-source, end-to-end distributed tracing system. Jaeger enables monitoring and troubleshooting transactions in complex distributed systems by tracking requests as they flow through multiple services. The application services and Kong API Gateway are instrumented with Jaeger client libraries that generate trace data including spans, which represent individual operations within a trace. Each span contains metadata such as operation names, start and finish timestamps, tags, and logs that provide context about the operation being performed. The Jaeger Collector aggregates these spans from multiple services, performing validation, indexing, and transformation before forwarding the data.

The traces flow through Amazon MSK for the same reliability benefits as the logging pipeline – providing durability, decoupling, and backpressure handling during high-volume periods. Jaeger Ingester then consumes traces from Amazon MSK and processes them for storage in the jaeger-index within OpenSearch Service.

This data collection and ingestion strategy provides complete end-to-end visibility and builds an observability system that enables SRE teams to monitor, troubleshoot, and optimize the services across the entire technology stack.

Storage tiering

To manage the log, metric, and trace data at scale—about 3TB generated daily—the solution implemented OpenSearch Service storage tiering to balance performance, retention, and cost. Zeta requires near real-time search and retrieval for at least a week, while retaining logs and traces for up to 10 years. Keeping this data in active clusters would impact search performance and significantly increase costs, so the solution uses the OpenSearch Service hot, UltraWarm, and cold storage tiers to optimize the data lifecycle. The following diagram illustrates storage tiering in OpenSearch Service.

Zeta CSN Storage Tiering

Hot storage is used for the most recent and frequently accessed data, supporting real-time indexing and low-latency queries. This tier relies on high-performance storage attached to standard data nodes, making it ideal for powering live dashboards and analytics where speed is critical. The solution uses AWS Graviton 2 powered m6g.4xlarge.search instance types to run the OpenSearch Service domain which provides upto 40% lower cost compared to x86 based instances. Each hot data node has an attached gp3 EBS volume to store indexes. Zeta maintains data in hot storage for 1 week.

UltraWarm storage serves as a cost-effective layer for older, read-only data that is queried less frequently but still needs to remain searchable. UltraWarm nodes use Amazon Simple Storage Service (Amazon S3) as the backing store with an integrated caching mechanism, to retain large volumes of data at a fraction of the cost of hot storage while still supporting interactive queries for historical analysis. Zeta uses ultrawarm1.large.search instance types in the UltraWarm storage tier and maintains data in UltraWarm storage for 15 days.

Cold storage is designed for long-term archival of infrequently accessed or compliance-driven data. Data in cold storage is detached from active compute resources and resides in Amazon S3, incurring minimal cost. When historical data needs to be queried, the indexes are attached to the UltraWarm nodes using OpenSearch API calls. This helps extracting historical data for audits, periodic research or forensic investigations without maintaining active compute for the entire retention period, thereby reducing storage cost.

OpenSearch Service automates index transitions between hot, UltraWarm, and cold storage tiers using Index State Management (ISM) policies. ISM policies specify the conditions and actions for each state, such as transitioning based on index age, size, or document count. When an index qualifies for a transition, ISM jobs—running every 5 to 8 minutes—evaluate the policy and move the index to the next tier. When indexes reach the UltraWarm threshold, they are migrated to UltraWarm nodes backed by Amazon S3, which reduces storage costs while keeping data accessible for queries. After the UltraWarm retention period, ISM archives the indexes to cold storage, detaching them from compute resources but allowing reattachment for future queries or compliance needs. This automated lifecycle management reduces operational overhead, optimizes storage costs, and maintains performance for both recent and historical data.

For observability data, new indexes are created in the hot tier, where they remain for 7 days to support fast ingestion and low-latency queries. After this period, ISM transitions these indexes to UltraWarm storage, where they are retained for an additional 15 days as read-only data, balancing cost with searchability.

Security

Security is the most critical part of the architecture. Zeta’s observability system implements multiple layers of protection for data confidentiality, integrity, and compliance with banking regulations, and is built using a zero-trust approach following the AWS shared responsibility model for OpenSearch Service:

  • Infrastructure security: The OpenSearch Service domain is deployed within a virtual private cloud (VPC) with private subnets, isolating it from direct internet access. Security groups enforce restrictive ingress rules, allowing access only from authorized sources. The OpenSearch Service domain uses encryption at rest through AWS Key Management Service (KMS). Data in transit is secured using TLS 1.3 encryption, so that log data, traces, and search queries remain protected during transmission. Service-to-service communication uses AWS Identity and Access Management (IAM) roles and encrypted connections, alleviating the need for hardcoded credentials.
  • Access control and authentication: The solution uses Amazon OpenSearch Service fine-grained access control(FGAC) integrated with IAM, where IAM serves as the authentication provider and FGAC handles authorization by mapping IAM roles to OpenSearch backend roles. This approach helps Zeta to control access permissions at the index and document level based on tenant requirements and user responsibilities. The data ingestion pipeline implements end-to-end security with Fluentd authenticating to Amazon MSK using IAM roles over encrypted connections. Amazon MSK clusters use encryption in transit and at rest, protecting log data throughout the streaming pipeline. Kubernetes RBAC policies restrict pod-to-pod communication and limit service account permissions.
  • Data privacy and tenant isolation: Each tenants’ data is maintained in logical separation in OpenSearch Service using tenant id. CSN implements tenant-aware authentication and authorization with FGAC, restricting users to their authorized tenants’ dashboards and data. Every API endpoint validates tenant context, so that users can only access data within their authorized scope. Importantly, no customer data is captured in the logs – only system metrics are used to build the monitoring system, adhering to banking security standards and best practices. User actions are audited and logged for compliance purposes, with audit trails maintained according to regulatory requirements.

This security framework enables the observability system meet the security requirements of core banking operations while maintaining operational efficiency and regulatory compliance across global industries.

Customer Service Navigator

CSN delivers SREs a powerful diagnostics interface engineered for high-efficiency monitoring, deep analysis, and rapid troubleshooting of system performance across distributed environments. The system ingests and processes telemetry data at sub-minute intervals, providing near-real-time metrics, traces, and logs from critical infrastructure components. Actionable, interactive visualizations—such as heatmaps, anomaly graphs, and dependency maps— helps SREs to quickly detect SLO breaches and drill down to granular root causes, often within a few minutes of an incident.

The following screenshot shows an example service health dashboard in CSN for an Olympus tenant.

Zeta CSN Service Health Dashboard

The following screenshot shows an example of the API performance insights dashboard in CSN.

Zeta CSN API Performance Dashboard

Business and technical benefits

The OpenSearch Service-based CSN System provides the following business and technical benefits:

  • Manual effort is reduced through automated Index State Management (ISM) and lifecycle policies, so that Zeta’s teams to focus on innovation
  • Automated lifecycle policies facilitate seamless retention and archiving of compliance data, reducing the risk of non-compliance
  • The system supports log retention for over 10 years to meet regulatory requirements for Zeta’s banking and financial services customers
  • Multiple layers of security—including encryption at rest and in transit, FGAC, and tenant isolation to protect customer data and support Zeta’s zero-trust architecture
  • By consolidating logs, traces, and metrics from disparate systems into OpenSearch, SRE teams can correlate events more effectively, thereby reducing troubleshooting efforts and achieving an 80% improvement in MTTR
  • Zeta achieved 99.999999999% data durability for archived logs stored in Amazon S3, providing long-term data integrity
  • Zstandard compression is being implemented to optimize long-term storage costs

Conclusion

CSN’s advanced correlation engine automatically associates related events across microservices, databases, network layers, and infrastructure, significantly streamlining root cause analysis. Integrated alerting and automated runbooks further reduce response times. Since implementing CSN, Zeta has achieved over an 80% reduction in MTTR, with incident response times decreasing from 30+ minutes to under 5 minutes. The service supports seamless multi-tenant monitoring, processes 3TB of machine-generated data daily, and is architected for petabyte-scale growth. Additionally, CSN helps Zeta meet regulatory requirements for retaining historical logs over several years while keeping storage costs under control. This has substantially improved operational resilience, increased service availability, and empowered teams to proactively resolve issues before they affect end users.

Ready to take your organization’s observability capabilities to the next level? Dive into the technical details of OpenSearch Service in the Amazon OpenSearch Developer Guide. Visit our new migration hub page for more prescriptive guidance on moving your workloads to OpenSearch Service.


About the authors

Deepesh DhapolaDeepesh Dhapola is a Senior Solutions Architect at AWS India, where he architects high-performance, resilient cloud solutions for financial services and fintech organizations. He specializes in using advanced AI technologies—including generative AI, intelligent agents, and the Model Context Protocol (MCP)—to design secure, scalable, and context-aware applications. With deep expertise in machine learning and a keen focus on emerging trends, Deepesh drives digital transformation by integrating cutting-edge AI capabilities to enhance operational efficiency and foster innovation for AWS customers. Beyond his technical pursuits, he enjoys quality time with his family and explores creative culinary techniques.

Shashidhar (Shashi) SoppinShashidhar (Shashi) Soppin is an accomplished Enterprise Architect and cloud transformation leader with over 24+ years of experience spanning regulated industries and high-growth technology environments. Currently steering strategic initiatives as Lead Architect at Zeta’s CTO office, Shashidhar has helped in building and led world-class engineering teams, driving innovation in cloud, security, and fintech domains. He has architected secure, scalable platforms—scaling user bases by 10x, enabling complex integrations for leading Bank’s migration to Zeta’s platforms, and pioneering Zero Trust frameworks that achieved outstanding regulatory compliance. A results-driven executive and former DMTS at Wipro, Shashidhar holds 25+ granted patents and has delivered multi-million dollar enterprise deals across domains including AI/ML. Renowned as a published author (“Essentials of Deep Learning”), frequent industry speaker, and hands-on innovator, he combines technical expertise with business acumen, propelling organizations toward robust, future-ready cloud ecosystems and operational excellence. Prior to Wipro he worked in IBM-ISL as well.

Anchal KansalAnchal Kansal is a Lead Site Reliability Engineer at Zeta, where she has spent the past four years building and scaling reliable, high-performance systems. With deep expertise in OpenSearch, observability platforms, and large-scale infrastructure, she focuses on ensuring uptime, performance, and operational efficiency. Anchal is passionate about solving complex reliability challenges and sharing practical insights with the engineering community.

Mano (Manochandra)Manochandra (Mano) is the Site Reliability Engineering (SRE) expert at Zeta, specializing in data management-oriented systems. With a deep understanding of large-scale distributed architectures, he has extensive experience designing, deploying, and maintaining resilient, production-grade OpenSearch systems. Mano is known for his proactive approach in optimizing infrastructure reliability and performance, as well as his ability to troubleshoot complex operational challenges. His expertise spans implementing automation, monitoring, and incident management best practices, making him a go-to resource for ensuring service availability and scalability at Zeta.

 Hitesh SubnaniHitesh Subnani is a FSI Solutions Architect at AWS India, where he works with customers to design and build architectures that deliver business value. He specializes in comprehensive observability and analytics systems, enabling organizations to gain deep insights from operational data. With expertise in search and analytics technologies, Hitesh focuses on scalable monitoring systems, real-time dashboards, and compliance-driven architectures for AWS customers in the financial sector.

Tarun ChakrabortyTarun Chakraborty is a Sr. Technical Account Manager (TAM) at AWS India, where he partners with leading banks and fintech organizations to accelerate their cloud transformation journeys. With over 15 years of experience in technology and financial services, he serves as a trusted advisor helping customers leverage AWS’s comprehensive suite of services to drive innovation and achieve their business objectives.
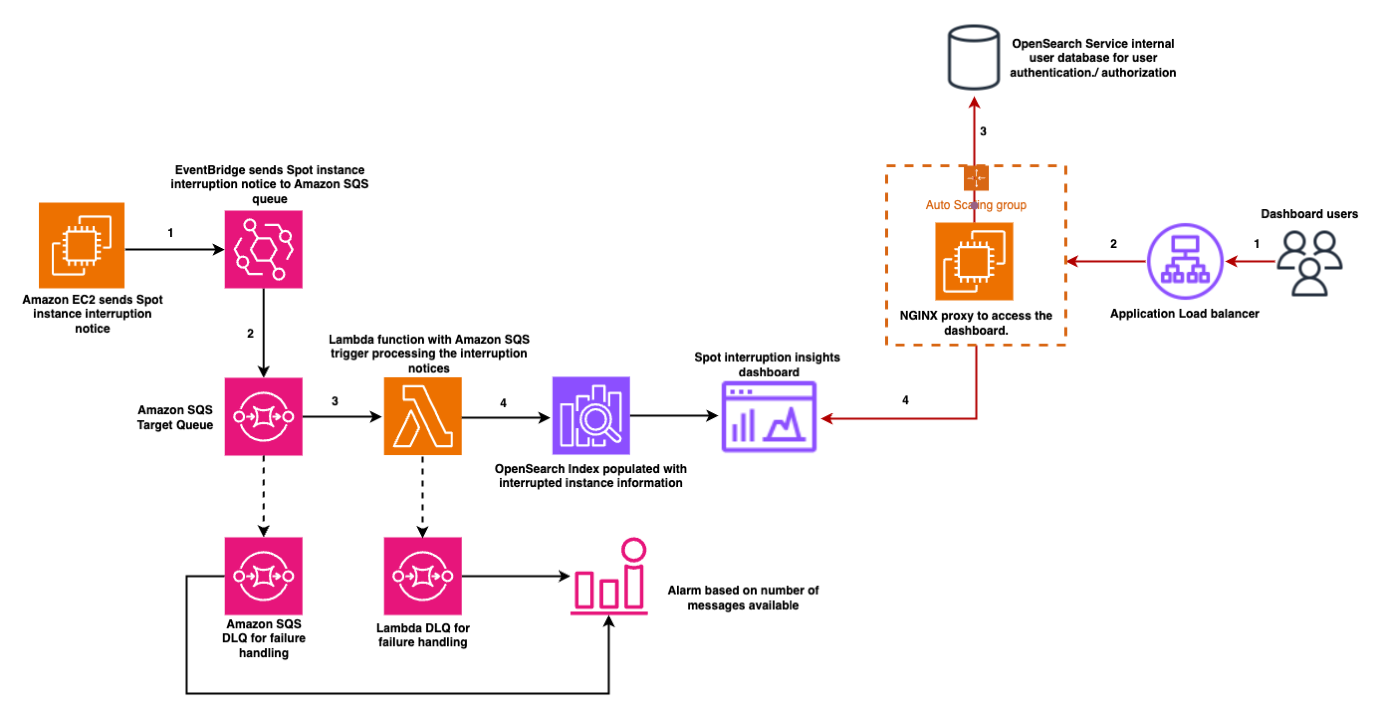
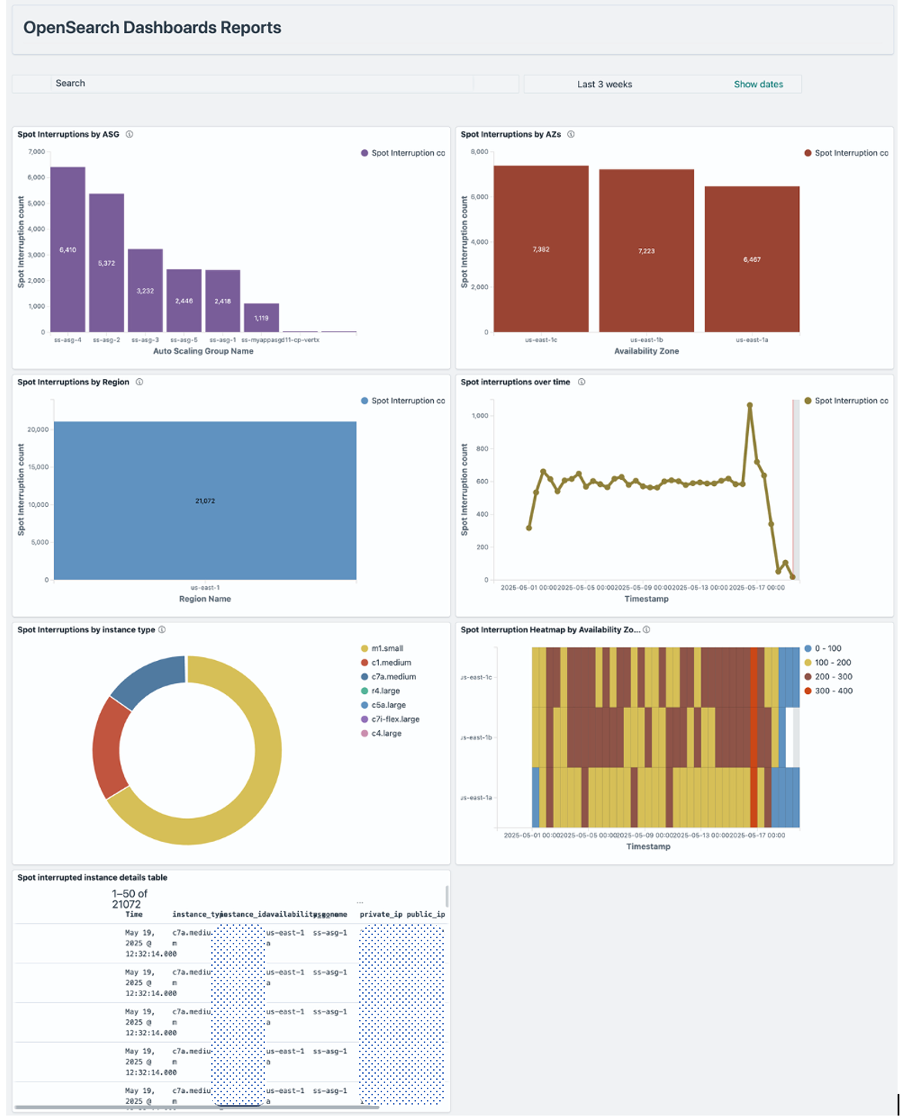
Build enterprise-scale log ingestion pipelines with Amazon OpenSearch Service

Post Syndicated from Akhil B original https://aws.amazon.com/blogs/big-data/build-enterprise-scale-log-ingestion-pipelines-with-amazon-opensearch-service/

Organizations of all sizes generate massive volumes of logs across their applications, infrastructure, and security systems to gain operational insights, troubleshoot issues, and maintain regulatory compliance. However, implementing log analytic solutions presents significant challenges, including complex data ingestion pipelines and the need to balance cost and performance while scaling to handle petabytes of data.

Amazon OpenSearch Service addresses these challenges by providing high-performance search and analytics capabilities, making it straightforward to deploy and manage OpenSearch clusters in the AWS Cloud without the infrastructure management overhead. A well-designed log analytics solution can help support proactive management in a variety of use cases, including debugging production issues, monitoring application performance, or meeting compliance requirements.

In this post, we share field-tested patterns for log ingestion that have helped organizations successfully implement logging at scale, while maintaining optimal performance and managing costs effectively.

Solution overview

Organizations can choose from several data ingestion architectures, such as:

Irrespective of the chosen pattern, a scalable log ingestion architecture should comprise the following logical layers:

  • Collect layer – This is the initial stage where logs are gathered from various sources, including application logs, system logs, and more.
  • Buffer layer – This layer acts as a temporary storage layer to handle spikes in log volume and prevents data loss during downstream processing issues. This layer also maintains system stability during high load.
  • Process layer – This layer transforms the unstructured logs into structured formats while adding relevant metadata and contextual information needed for effective analysis.
  • Store layer – This layer is the final destination for processed logs (OpenSearch in this case), which supports various access patterns, including querying, historical analysis, and data visualization.

OpenSearch Ingestion offers a purpose-built, fully managed experience that simplifies the data ingestion process. In this post, we focus on using OpenSearch Ingestion to load logs from Amazon Simple Storage Service (Amazon S3) into an OpenSearch Service domain, a common and efficient pattern for log analytics.

OpenSearch Ingestion is a fully managed, serverless data ingestion service that streamlines the process of loading data into OpenSearch Service domains or Amazon OpenSearch Serverless collections. It’s powered by Data Prepper, an open source data collector that filters, enriches, transforms, normalizes, and aggregates data for downstream analysis and visualization.

OpenSearch Ingestion uses pipelines as a mechanism that consists of the following major components:

  • Source – The input component of a pipeline. It defines the mechanism through which a pipeline consumes records.
  • Buffer – A persistent, disk-based buffer that stores data across multiple Availability Zones to enhance durability. OpenSearch Ingestion dynamically allocates OCUs for buffering, which increases pricing as you may need additional OCUs to maintain ingestion throughput.
  • Processors – The intermediate processing units that can filter, transform, and enrich records into a desired format before publishing them to the sink. The processor is an optional component of a pipeline.
  • Sink – The output component of a pipeline. It defines one or more destinations to which a pipeline publishes records. A sink can also be another pipeline, so you can chain multiple pipelines together.

Because of its serverless nature, OpenSearch Ingestion automatically scales to accommodate varying workload demands, alleviating the need for manual infrastructure management while providing built-in monitoring capabilities. Users can focus on their data processing logic rather than spending time on operational complexities, making it an efficient solution for managing data pipelines in OpenSearch environments.

The following diagram illustrates the architecture of the log ingestion pipeline.

Let’s walk through how this solution processes Apache logs from ingestion to visualization:

  1. The source application generates Apache logs that need to be analyzed and stores them in an S3 bucket, which acts as the central storage location for incoming log data. When a new log file is uploaded to the S3 bucket (ObjectCreate event), Amazon S3 automatically triggers an event notification that is configured to send messages to a designated Amazon Simple Queue Service (Amazon SQS) queue.
  2. The SQS queue reliably manages and tracks the notifications of new files uploaded to Amazon S3, making sure the file event is delivered to the OpenSearch Ingestion pipeline. A dead-letter queue (DLQ) is configured to capture failed event processing.
  3. The OpenSearch Ingestion pipeline monitors the SQS queue, retrieving messages that contain information about newly uploaded log files. When a message is received, the pipeline reads the corresponding log file from Amazon S3 for processing.
  4. After the log file is retrieved, the OpenSearch Ingestion pipeline parses the content, and uses the OpenSearch Bulk API to efficiently ingest the processed log data into the OpenSearch Service domain, where it becomes available for search and analysis.
  5. The ingested data can be visualized and analyzed through OpenSearch Dashboards, which provides a user-friendly interface for creating custom visualizations, dashboards, and performing real-time analysis of the log data with features like search, filtering, and aggregations.

In the following sections, we guide you through the steps to ingest application log files from Amazon S3 into OpenSearch Service using OpenSearch Ingestion. Additionally, we demonstrate how to visualize the ingested data using OpenSearch Dashboards.

Prerequisites

This post assumes you have the following:

Deploy the solution

The solution uses a Python AWS Cloud Development Kit (AWS CDK) project to deploy an OpenSearch Service domain and associated components. This project demonstrates event-based data ingestion into the OpenSearch Service domain in a no code approach using OpenSearch Ingestion pipelines.

The deployment is automated using the AWS CDK and comprises the following steps:

  1. Clone the GitHub repo.
    git clone [email protected]:aws-samples/sample-log-ingestion-pipeline-for-amazon-opensearch-service.git

  2. Create a virtual environment and install the Python dependencies:
python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
  1. Update the following environment variables in cdk.json:
    1. domain_name: The OpenSearch domain to be created in your AWS account.
    2. user_name: The user name for the internal primary user to be created within the OpenSearch domain.
    3. user_password: The password for the internal primary user.

This deployment creates a public-facing OpenSearch domain but is secured through fine-grained access control (FGAC). For production workloads, consider deploying within a virtual private cloud (VPC) with additional security measures. For more information, see Security in Amazon OpenSearch Service.

  1. Bootstrap the AWS CDK stack and initiate the deployment. Provide your AWS account number and the AWS Region where you want deploy the solution:
cdk bootstrap <Account ID>/<region>
cdk deploy --all

The process takes about 30–45 minutes to complete.

Verify the solution resources

When the previous steps are complete, you can check for the created resources.

You can confirm the existence of the stacks on the AWS CloudFormation console. As shown in the following screenshot, the CloudFormation stacks have been created and deployed by cdk bootstrap and cdk deploy.

image-2

On the OpenSearch Service console, under Managed clusters in the navigation pane, choose Domains. You can confirm the domain created.

image-3

On the OpenSearch Service console, under Ingestion in the navigation pane, choose Pipelines. You can see the pipeline apache-log-pipeline created.

image-4

Configure security options

To configure your security roles, complete the following steps:

  1. On the AWS CloudFormation console, open the stack CdkIngestionStack, and on the Outputs tab, copy the Amazon Resource Name (ARN) of osi-pipeline-role.

image-5

  1. Open the OpenSearch Service console in the deployed Region within your AWS account and choose the domain you created.
  2. Choose the link for OpenSearch Dashboards URL.
  3. In the login prompt, enter the user credentials that were provided in cdk.json.

After a successful login, the OpenSearch Dashboards console will be displayed.

  1. If you’re prompted to select a tenant, select the Global tenant.
  2. In the Security options, navigate to the Roles section and choose the all_access role.
  3. On the all_access role page, navigate to mapped_users and choose Manage.
  4. Choose Add another backend role under Backend roles and enter the IAM role ARN you copied.
  5. Confirm by choosing Map.

image-6

Create an index template

The next step is to create an index template. Complete the following steps:

  1. On the Dev Tools console, copy the contents of the file index_template.txt within the opensearch_object directory.
  2. Enter the code in the Dev Tools console.

This index template defines the mapping and settings for our OpenSearch index.

  1. Choose the play icon to submit the request and create a template.

image-7

  1. In the Dashboard Management section, choose Saved Objects and choose Import.
  2. Choose Import and choose the apache_access_log_dashboard.ndjson file within the opensearch_object directory.
  3. Choose Check for existing objects.
  4. Choose Automatically overwrite conflicts and choose Import.

Ingest data

Now you can proceed with the data ingestion.

  1. On the Amazon S3 console, open the S3 bucket opensearch-logging-blog-<Account ID>.
  2. Upload the data file apache_access_log.gz (within the apache_log_data directory). The file can be uploaded in any prefix.

For this solution, we use Apache access logs as our example data source. Although this pipeline is configured for Apache log format, it can be modified to support other log types by adjusting the pipeline configuration. See Overview of Amazon OpenSearch Ingestion for details about configuring different log formats.

  1. After a few minutes, navigate to the Discover tab in OpenSearch Dashboards, where you can find that the data is ingested.
  2. Confirm that the apache* index pattern is selected.

image-8

  1. 5. On the Dashboards tab, choose Apache Log Dashboard.

The dashboard will be populated by the data and visuals should be displayed.

image-10

Operational best practices

When designing your log analytics platform on OpenSearch Service, make sure you follow the recommended operational best practices for cluster configuration, data management, performance, monitoring, and cost optimization. For detailed guidance, refer to Operational best practices for Amazon OpenSearch Service.

Clean up

To avoid ongoing charges for the resources that you created, delete them by completing the following steps:

  1. On the Amazon S3 console, open the bucket opensearch-logging-blog-<Account ID> and choose Empty.
  2. Follow the prompts to delete the contents of the bucket.
  3. Delete the AWS CDK stacks using the following command:
cdk destroy --all --force

Conclusion

As organizations continue to generate increasing volumes of log data, having a well-architected logging solution becomes crucial for maintaining operational visibility and meeting compliance requirements.

Implementing a robust logging infrastructure requires careful planning. In this post, we explored a field-tested approach in building a scalable, efficient, and cost-effective logging solution using OpenSearch Ingestion.

This solution serves as a starting point that can be customized based on specific organizational needs while maintaining the core principles of scalability, reliability, and cost-effectiveness.

Remember that logging infrastructure is not a “set-and-forget” system. Regular monitoring, periodic reviews of storage patterns, and adjustments to index management policies will help make sure your logging solution continues to serve your organization’s evolving needs effectively.

To dive deeper into OpenSearch Ingestion implementation, explore our comprehensive Amazon OpenSearch Service Workshops, which include hands-on labs and reference architectures. For additional insights, see Build a serverless log analytics pipeline using Amazon OpenSearch Ingestion with managed Amazon OpenSearch Service. You can also visit our Migration Hub if you’re ready to migrate legacy or self-managed workloads to OpenSearch Service.


About the authors

Akhil B is a Data Analytics Consultant at AWS Professional Services, specializing in cloud-based data solutions. He partners with customers to design and implement scalable data analytics platforms, helping organizations transform their traditional data infrastructure into modern, cloud-based solutions on AWS. His expertise helps organizations optimize their data ecosystems and maximize business value through modern analytics capabilities.

Ramya Bhat is a Data Analytics Consultant at AWS, specializing in the design and implementation of cloud-based data platforms. She builds enterprise-grade solutions across search, data warehousing, and ETL that enable organizations to modernize data ecosystems and derive insights through scalable analytics. She has delivered customer engagements across healthcare, insurance, fintech, and media sectors.

Chanpreet Singh is a Senior Consultant at AWS, specializing in the Data and AI/ML space. He has over 18 years of industry experience and is passionate about helping customers design, prototype, and scale Big Data and Generative AI applications using AWS native and open-source tech stacks. In his spare time, Chanpreet loves to explore nature, read, and spend time with his family.

Cluster manager communication simplified with Remote Publication

Post Syndicated from Himshikha Gupta original https://aws.amazon.com/blogs/big-data/cluster-manager-communication-simplified-with-remote-publication/

Amazon OpenSearch Service has taken a significant leap forward in scalability and performance with the introduction of support for 1,000-node OpenSearch Service domains capable of handling 500,000 shards with OpenSearch Service version 2.17. This breakthrough is made possible by multiple features, including Remote Publication, which introduces an innovative cluster state publication mechanism that enhances scalability, availability, and durability. It uses the remote cluster state feature as the base. This feature provides durability and makes sure metadata is not lost even when the majority of the cluster manager nodes fail permanently. By using a remote store for cluster state publication, OpenSearch Service can now support clusters with a higher number of nodes and shards.

The cluster state is an internal data structure that contains cluster information. The elected cluster manager node manages this state. It’s distributed to follower nodes through the transport layer and stored locally on each node. A follower node can be a data node, a coordinator node or a non-elected cluster manager node. However, as the cluster grows, publishing the cluster state over the transport layer becomes challenging. The increasing size of the cluster state consumes more network bandwidth and blocks transport threads during publication. This can impact scalability and availability. This post explains cluster state publication, Remote Publication, and their benefits in improving durability, scalability, and availability.

How did cluster state publication work before Remote Publication?

The elected cluster manager node is responsible for maintaining and distributing the latest OpenSearch cluster state to all the follower nodes. The cluster state updates when you create indexes and update mappings, or when internal actions like shard relocations occur. Distribution of the updates follows a two-phase process: publish and commit. In the publish phase, the cluster manager sends the updated state to the follower nodes and saves a copy locally. After a majority (more than half) of the eligible cluster manager nodes acknowledge this update, the commit phase begins, where the follower nodes are instructed to apply the new state.

To optimize performance, the elected cluster manager sends only the changes since the last update, referred to as the diff state, reducing data transfer. However, if a folllower node is out of sync or new to the cluster, it might reject the diff state. In such cases, the cluster manager sends the full cluster state to those follower nodes.

The following diagram depicts the cluster state publication flow.

Sequence of steps between the cluster manager node and a follower node demonstrating the cluster state publication over transport layer

The workflow consists of the following steps:

  1. The user invokes an admin API such as create index.
  2. The elected cluster manager node computes the cluster state for the admin API request.
  3. The elected cluster manager node sends the cluster state publish request to follower nodes.
  4. The follower nodes respond with an acknowledgement to the publish request.
  5. The elected cluster manager node persists the cluster state to the disk.
  6. The elected cluster manager node sends the commit request to follower nodes.
  7. The follower nodes respond with an acknowledgement to the commit request.

We’ve observed stable cluster operations with this publication flow up to 200 nodes or 75,000 shards. However, as the cluster state grows in size with more indexes, shards, and nodes, it starts consuming high network bandwidth and blocking transport threads for a longer duration during publication. Additionally, it becomes CPU and memory intensive for the elected cluster manager to transmit to the follower nodes, often impacting publication latency. The increased latency can lead to a high pending task count on the elected cluster manager. This can cause request timeouts, or in severe cases, cluster manager failure, creating a cluster outage.

Using a remote store for cluster state publication improved availability and scalability

With Remote Publication, cluster state updates are transmitted through an Amazon Simple Storage Service (Amazon S3) bucket as the remote store, rather than transmitting the state over the transport layer. When the elected cluster manager updates the cluster state, it uploads the new state to Amazon S3 in addition to persisting on disk. The cluster manager uploads a manifest file, which keeps track of the entities and which entities changed from their previous state. Similarly, follower nodes download the manifest from Amazon S3 and can decide if it needs the full state or only changed entities. This has two benefits: reduced cluster manager resource usage and faster transport thread availability.

Creating new domains or upgrading from existing OpenSearch Service versions to 2.17 or above, or applying the service patch to an existing 2.17 or above domain, enables Remote Publication by default, This provides seamless migration with the remote state. This is enabled by default for SLA clusters, with or without remote-backed storage. Let’s dive into some details of this design and understand how it works internally.

How is the remote store modeled for scalability?

Having scalable and efficient Amazon S3 storage is essential for Remote Publication to work seamlessly. The cluster state has multiple entities, which get updated at different frequencies. For example, cluster node data only changes if a new node joins the cluster or an old node leaves the cluster, which usually happens during blue/green deployments or node replacements. However, shard allocation can change multiple times a day based on index creations, rollovers, or internal service triggered relocations. The storage schema needs to be able to handle these entities in a way that a change in one entity doesn’t impact another entity. A manifest file keeps track of the entities. Each cluster state entity has its own separate file, like one for templates, one for cluster settings, one for cluster nodes, and so on. For entities that scale with the number of indexes, like index metadata and index shard allocation, per-index files are created to make sure changes in an index can be uploaded and downloaded independently. The manifest file keeps track of paths to these individual entity files. The following code shows a sample manifest file. It contains the details of the granular cluster state entities’ files uploaded to Amazon S3 along with some basic metadata.

{
    "term": 5,
    "version": 10,
    "cluster_uuid": "dsgYj10Nkso7",
    "state_uuid": "dlu34Dh2Hiq",
    "node_id": "7rsyg5FbSeSt",
    "node_version": "3000099",
    "committed": true,
    "indices": [{
        "index_name": "index1",
        "uploaded_filename": "index1-s3-key"
    }, {
        "index_name": "index2",
        "uploaded_filename": "index2-s3-key"
    }],
    "indices_routing": [{
        "index_name": "index1",
        "uploaded_filename": "index1-routing-s3-key"
    }, {
        "index_name": "index2",
        "uploaded_filename": "index2-routing-s3-key"
    }],
    "uploaded_settings_metadata": {
        "uploaded_filename": "settings-s3-key"
    },
    "diff_manifest": {
        "from_state_uuid": "aRiq3oEip",
        "to_state_uuid": "dlu34Dh2Hiq",
        "metadata_diff": {
            "settings_metadata_diff": true,
            "indices_diff": {
                "upserts": ["index1"],
                "deletes": ["index2"]
            }
        },
        "routing_table_diff": {
            "upserts": ["index1"],
            "deletes": ["index2"],
            "diff": "indices-routing-diff-s3-key"
        }
    }
}

In addition to keeping track of cluster state components, the manifest file also keeps track of what entities changed compared to the last state, which is the diff manifest. In the preceding code, diff manifest has a section for metadata diff and routing table diff. This signifies that between these two versions of the cluster state, these entities have changed.

We also keep a separate shard diff file specifically for shard allocation. Because multiple shards for different indexes can be relocated in a single cluster state update, having this shard diff file further reduces the number of files to download.

This configuration provides the following benefits:

  • Separate files help prevent bloating a single document
  • Per-index files reduces the number of updates and effectively reduces the network bandwidth usage, because most updates affect only a few indexes
  • Having a diff tracker makes downloads on nodes efficient because only limited data needs to be downloaded

To support the scale and high request rate to Amazon S3, we use Amazon S3 pre-partitioning, so we can scale proportionally with the number of clusters and indexes. For managing storage size, an asynchronous scheduler is added, which cleans up stale files and keeps only the last 10 recently updated documents. After a cluster is deleted, a domain sweeper job removes the files for that cluster after a few days.

Remote Publication overview

Now that you understand how cluster state is persisted in Amazon S3, let’s see how it is used during the publication workflow. When a cluster state update occurs, the elected cluster manager uploads changed entities to Amazon S3 in parallel, with the number of concurrent uploads determined by a fixed thread pool. It then updates and uploads a manifest file with diff details and file paths.

During the publish phase, the elected cluster manager sends the manifest path, term, and version to follower nodes using a new remote transport action. When the elected cluster manager changes, the newly elected cluster manager increments the term which signifies the number of times a new cluster manager election has occurred. The elected cluster manager increments the cluster state version when the cluster state is updated. You can use these two components to identify cluster state progression and make sure nodes operate with the same understanding of the cluster’s configuration. The follower nodes download the manifest, determine if they need a full state or just the diff, and then download the required files from Amazon S3 in parallel. After the new cluster state is computed, follower nodes acknowledge the elected cluster manager.

In the commit phase, the elected cluster manager updates the manifest, marking it as committed, and instructs follower nodes to commit the new cluster state. This process provides efficient distribution of cluster state updates, especially in large clusters, by minimizing direct data transfer between nodes and using Amazon S3 for storage and retrieval. The following diagram depicts the Remote Publication flow when an index creation triggers a cluster state update.

Sequence of steps between the cluster manager node, the follower nodes, and a remote store such as Amazon S3 depicting the remote cluster state publication

The workflow consists of the following steps:

  1. The user invokes an admin API such as create index.
  2. The elected cluster manager node uploads the index metadata and routing table files in parallel to the configured remote store.
  3. The elected cluster manager node uploads the manifest file containing the details of the metadata files to the remote store.
  4. The elected cluster manager sends the remote manifest file path to the follower nodes.
  5. The follower node downloads the manifest file from the remote store.
  6. The follower nodes download the index metadata and routing table files from the remote store in parallel.

Failure detection in publication

Remote Publication brings in a significant change to how publication works and how the cluster state is managed. Issues in file creation, publication, or downloading and creating cluster state on follower nodes can have a potential impact on the cluster. To make sure the new flow works as expected, a checksum validation is added to the publication flow. On the elected cluster manager, after creating a new cluster state, a checksum is created for individual entities and the overall cluster state and added to the manifest. On follower nodes, after the cluster state is created after download, a checksum is created again and matched against the checksum from the manifest. A mismatch in checksums means the cluster state on the follower node is different from that on the elected cluster manager. In the default mode, the service only logs which entity is failing the checksum match and lets the cluster state persist. For further debugging, checksum match supports different modes, where it can download the complete state and find the diff between two states in trace mode, or fail the publication request in failure mode.

Recovery from failures

With remote state, quorum loss is recovered by using the cluster state from the remote store. Without remote state, the cluster manager might lose metadata, leading to data loss for your cluster. However, the cluster manager can now use the last persisted state to help prevent metadata loss in the cluster. The following diagram illustrates the states of a cluster before a quorum loss, during a quorum loss, and after the quorum loss recovery happens using a remote store.

The states of a cluster before a quorum loss, during a quorum loss, and after the quorum loss recovery happens using remote store

Benefits

In this section, we discuss some of the solution benefits.

Scalability and availability

Remote Publication significantly reduces the CPU, memory, and network overhead for the elected cluster manager when transmitting the state to the follower nodes. Additionally, transport threads responsible for sending publish requests to follower nodes are made available more quickly, because the remote publish request size is smaller. The publication request size remains consistent irrespective of the cluster state size, giving consistent publication performance. This enhancement enables OpenSearch Service to support larger clusters of up to 1,000 nodes and a higher number of shards per node, without overwhelming the elected cluster manager. With reduced load on the cluster manager, its availability improves, so it can more efficiently serve admin API requests.

Durability

With the cluster state being persisted to Amazon S3, we get Amazon S3 durability. Clusters suffering quorum loss due to replacement of cluster manager nodes can hydrate with the remote cluster state and recover from quorum loss. Because Amazon S3 has the last committed cluster state, there is no data loss on recovery.

Cluster state publication performance

We tested the elected cluster manager performance in a 1,000-node domain containing 500,000 shards. We compared two versions: the new Remote Publication system vs. the older cluster state publication system. Both clusters were operated with the same workload for a few hours. The following are some key observations:

  • Cluster state publication time reduced from an average of 13 seconds to 4 seconds, which is a three-fold improvement
  • Network out reduced from an average of 4 GB to 3 GB
  • Elected cluster manager resource utilization showed significant improvement, with JVM dropping from an average of 40% to 20% and CPU dropping from 50% to 40%

We tested on a 100-node cluster as well and saw performance improvements with the increase in the size of the cluster state. With 50,000 shards, the uncompressed cluster state size increased to 600 MB. The following observations were made during cluster state update when compared to a cluster without Remote Publication:

  • Max network out traffic reduced from 11.3 GB to 5.7 GB (approximately 50%)
  • Average elected cluster manager JVM usage reduced from 54% to 35%
  • Average elected cluster manager CPU reduced from 33% to 20%

Contributing to open source

OpenSearch is an open source, community-driven software. You can find code for the Remote Publication feature in the project’s GitHub repository. Some of the notable GitHub pull requests have been added inline to the preceding text. You can find the RFCs for remote state and remote state publication in the project’s GitHub repository. A more comprehensive list of pull requests is attached in the meta issues for remote state, remote publication, and remote routing table.

Looking ahead

The new Remote Publication architecture enables teams to build additional features and optimizations using the remote store:

  • Faster recovery after failures – With the new architecture, we have the last successful cluster state in Amazon S3, which can be downloaded on the new cluster manager. At the time of writing, only cluster metadata gets restored on recovery and then the elected cluster manager tries to build shard allocation by contacting the data nodes. This takes up a lot of CPU and memory for both the cluster manager and data nodes, in addition to the time taken to collate the data to build the allocation table. With the last successful shard allocation available in Amazon S3, the elected cluster manager can download the data, build the allocation table locally, and then update the cluster state to the follower nodes, making recovery faster and less resource-intensive.
  • Lazy loading – The cluster state entities can be loaded as needed instead of all at once. This approach reduces the average memory usage on a follower node and is expected to speed up cluster state publication.
  • Node-specific metadata – At present, every follower node downloads and loads the entire cluster state. However, we can optimize this by modifying the logic so that a data node only downloads the index metadata and routing table for the indexes it contains.
  • Optimize cluster state downloads – There is an opportunity to optimize the downloading of cluster state entities. We are exploring compression and serialization techniques to minimize the amount of data transmitted.
  • Restoring to an older state – The service keeps the cluster state for the last 10 updates. This can be used to restore the cluster to a previous state in case the state gets corrupted.

Conclusion

Remote Publication makes cluster state publication faster and more robust, significantly improving cluster scalability, reliability, and recovery capabilities, potentially reducing customer incidents and operational overhead. This change in architecture enables further improvements in elected cluster manager performance and making domains more durable, especially for larger domains where cluster manager operations become heavy as the number of indexes and nodes increase. We encourage you to upgrade to the latest version to take advantage of these improvements and share your experience with our community.


About the authors

Himshikha Gupta is a Senior Engineer with Amazon OpenSearch Service. She is excited about scaling challenges with distributed systems. She is an active contributor to OpenSearch, focused on shard management and cluster scalability

Sooraj Sinha is a software engineer at Amazon, specializing in Amazon OpenSearch Service since 2021. He has worked on multiple core components of OpenSearch, including indexing, cluster management, and cross-cluster replication. His contributions have focused on improving the availability, performance, and durability of OpenSearch.

Boosting search relevance: Automatic semantic enrichment in Amazon OpenSearch Serverless

Post Syndicated from Jon Handler original https://aws.amazon.com/blogs/big-data/boosting-search-relevance-automatic-semantic-enrichment-in-amazon-opensearch-serverless/

Traditional search engines rely on word-to-word matching (referred to as lexical search) to find results for queries. Although this works well for specific queries such as television model numbers, it struggles with more abstract searches. For example, when searching for “shoes for the beach,” a lexical search merely matches individual words “shoes,” “beach,” “for,” and “the” in catalog items, potentially missing relevant products like “water-resistant sandals” or “surf footwear” that don’t contain the exact search terms.

Large language models (LLMs) create dense vector embeddings for text that expand retrieval beyond individual word boundaries to include the context in which words are used. Dense vector embeddings capture the relationship between shoes and beaches by learning how often they occur together, enabling better retrieval for more abstract queries through what is called semantic search.

Sparse vectors combine the benefits of lexical and semantic search. The process starts with a WordPiece tokenizer to create a limited set of tokens from text. A transformer model then assigns weights to these tokens. During search, the system calculates the dot-product of the weights on the tokens (from the reduced set) from the query with tokens from the target document. You get a blended score from the terms (tokens) whose weights are high for both the query and the target. Sparse vectors encode semantic information, like dense vectors, and supply word-to-word matching through the dot-product, giving you a hybrid lexical-semantic match. For a detailed understanding of sparse and dense vector embeddings, visit Improving document retrieval with sparse semantic encoders in the OpenSearch blog.

Automatic semantic enrichment for Amazon OpenSearch Serverless makes implementing semantic search with sparse vectors effortless. You can now experiment with search relevance improvements and deploy to production with only a few clicks, requiring no long-term commitment or upfront investment. In this post, we show how automatic semantic enrichment removes friction and makes the implementation of semantic search for text data seamless, with step-by-step instructions to enhance your search functionality.

Automatic semantic enrichment

You could already enhance search relevance scoring beyond OpenSearch’s default lexical scoring with the Okapi BM25 algorithm, integrating dense vector and sparse vector models for semantic search using OpenSearch’s connector framework. However, implementing semantic search in OpenSearch Serverless has been complex and costly, requiring model selection, hosting, and integration with an OpenSearch Serverless collection.

Automatic semantic enrichment lets you automatically encode your text fields in your OpenSearch Serverless collections as sparse vectors by just setting the field type. During ingestion, OpenSearch Serverless automatically processes the data through a service-managed machine learning (ML) model, converting text to sparse vectors in native Lucene format.

Automatic semantic enrichment supports both English-only and multilingual options. The multilingual variant supports the following languages: Arabic, Bengali, Chinese, English, Finnish, French, Hindi, Indonesian, Japanese, Korean, Persian, Russian, Spanish, Swahili, and Telugu.

Model details and performance

Automatic semantic enrichment uses a service-managed, pre-trained sparse model that works effectively without requiring custom fine-tuning. The model analyzes the fields you specify, expanding them into sparse vectors based on learned associations from diverse training data. The expanded terms and their significance weights are stored in native Lucene index format for efficient retrieval. We’ve optimized this process using document-only mode, where encoding happens only during data ingestion. Search queries are merely tokenized rather than processed through the sparse model, making the solution both cost-effective and performant.

Our performance validation during feature development used the MS MARCO passage retrieval dataset, featuring passages averaging 334 characters. For relevance scoring, we measured average Normalized discounted cumulative gain (NDCG) for the first 10 search results (ndcg@10) on the BEIR benchmark for English content and average ndcg@10 on MIRACL for multilingual content. We assessed latency through client-side, 90th-percentile (p90) measurements and search response p90 took values. These benchmarks provide baseline performance indicators for both search relevance and response times.

The following table shows the automatic semantic enrichment benchmark.

Language Relevance improvement P90 search latency
English 20.0% over lexical search 7.7% lower latency over lexical search (bm25 is 26 ms, and automatic semantic enrichment is 24 ms)
Multilingual 105.1% over lexical search 38.4% higher latency over lexical search (bm25 is 26 ms, and automatic semantic enrichment is 36 ms)

Given the unique nature of each workload, we encourage you to evaluate this feature in your development environment using your own benchmarking criteria before making implementation decisions.

Pricing

OpenSearch Serverless bills automatic semantic enrichment based on OpenSearch Compute Units (OCUs) consumed during sparse vector generation at indexing time. You’re charged only for actual usage during indexing. You can monitor this consumption using the Amazon CloudWatch metric SemanticSearchOCU. For specific details about model token limits and volume throughput per OCU, visit Amazon OpenSearch Service Pricing.

Prerequisites

Before you create an automatic semantic enrichment index, verify that you’ve been granted the necessary permissions for the task. Contact an account administrator for assistance if required. To work with automatic semantic enrichment in OpenSearch Serverless, you need the account-level AWS Identity and Access Management (IAM) permissions shown in the following policy. The permissions serve the following purposes:

  • The aoss:*Index IAM permissions is used to create and manage indices.
  • The aoss:APIAccessAll IAM permission is used to perform OpenSearch API operations.
{
"Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
              "aoss:CreateIndex",
              "aoss:GetIndex",
              "aoss:APIAccessAll",
            ],
            "Resource": "<ARN of your Serverless Collection>"
        }
    ]
}

You also need an OpenSearch Serverless data access policy to create and manage Indices and associated resources in the collection. For more information, visit Data access control for Amazon OpenSearch Serverless in the OpenSearch Serverless Developer Guide. Use the following policy:

[
    {
        "Description": "Create index permission",
        "Rules": [
            {
                "ResourceType": "index",
                "Resource": ["index/<collection_name>/*"],
                "Permission": [
                  "aoss:CreateIndex", 
                  "aoss:DescribeIndex",                  
"aoss:ReadDocument",
    "aoss:WriteDocument"
                ]
            }
        ],
        "Principal": [
            "arn:aws:iam::<account_id>:role/<role_name>"
        ]
    },
    {
        "Description": "Create pipeline permission",
        "Rules": [
            {
                "ResourceType": "collection",
                "Resource": ["collection/<collection_name>"],
                "Permission": [
                  "aoss:CreateCollectionItems",
                  "aoss:"
                ]
            }
        ],
        "Principal": [
            "arn:aws:iam::<account_id>:role/<role_name>"
        ]
    },
    {
        "Description": "Create model permission",
        "Rules": [
            {
                "ResourceType": "model",
                "Resource": ["model/<collection_name>/*"],
                "Permission": ["aoss:CreateMLResources"]
            }
        ],
        "Principal": [
            "arn:aws:iam::<account_id>:role/<role_name>"
        ]
    },
]

To access private collections, set up the following network policy:

[
   {
      "Description":"Enable automatic semantic enrichment in private collection",
      "Rules":[
         {
            "ResourceType":"collection",
            "Resource":[
               "collection/<collection_name>"
            ]
         }
      ],
      "AllowFromPublic":false,
      "SourceServices":[
         "aoss.amazonaws.com"
      ],
   }
]

Set up an automatic semantic enrichment index

To set up an automatic semantic enrichment index, follow these steps:

  1. To create an automatic semantic enrichment index using the AWS Command Line Interface (AWS CLI), use the create-index command:
aws opensearchserverless create-index \
    --id <collection_id> \
    --index-name <index_name> \
    --index-schema <index_body>
  1. To describe the created index, use the following command:
aws opensearchserverless create-index \
    --id <collection_id> \
    --index-name <index_name> 

You can also use AWS CloudFormation templates (Type: AWS::OpenSearchServerless::CollectionIndex) or the AWS Management Console to create semantic search during collection provisioning as well as after the collection is created.

Example: Index setup for product catalog search

This section shows how to set up a product catalog search index. You’ll implement semantic search on the title_semantic field (using an English model). For the product_id field, you’ll maintain default lexical search functionality.

In the following index-schema, the title_semantic field has a field type set to text and has parameter semantic_enrichment set to status ENABLED. Setting the semantic_enrichment parameter enables automatic semantic enrichment on the title_semantic field. You can use the language_options field to specify either english or multi-lingual. For this post, we generate a nonsemantic title field named title_non_semantic. Use the following code:

aws opensearchserverless create-index \
    --id XXXXXXXXX \
    --index-name 'product-catalog' \
    --index-schema '{
    "mappings": {
        "properties": {
            "product_id": {
                "type": "keyword"
            },
            "title_semantic": {
                "type": "text",
                "semantic_enrichment": {
                    "status": "ENABLED",
                    "language_options": "english"
                }
            },
            "title_non_semantic": {
                "type": "text"
            }
        }
    }
}'

Data ingestion

After the index is created, you can ingest data through standard OpenSearch mechanisms, including client libraries, REST APIs, or directly through OpenSearch Dashboards. Here’s an example of how to add multiple documents using bulk API in OpenSearch Dashboards Dev Tools:

POST _bulk
{"index": {"_index": "product-catalog"}}
{"title_semantic": "Red shoes", "title_non_semantic": "Red shoes", "product_id": "12345" }
{"index": {"_index": "product-catalog"}}
{"title_semantic": "Black shirt", "title_non_semantic": "Black shirt", "product_id": "6789" }
{"index": {"_index": "product-catalog"}}
{"title_semantic": "Blue hat", "title_non_semantic": "Blue hat", "product_id": "0000" }

Search against automatic semantic enrichment index

After the data is ingested, you can query the index:

POST product-catalog/_search?size=1
{
  "query": {
    "match":{
      "title_semantic":{
        "query": "crimson footwear"
      }
    }
  }
}

The following is the response:

{
    "took": 240,
    "timed_out": false,
    "_shards": {
        "total": 0,
        "successful": 0,
        "skipped": 0,
        "failed": 0
    },
    "hits": {
        "total": {
            "value": 1,
            "relation": "eq"
        },
        "max_score": 7.6092715,
        "hits": [
            {
                "_index": "product-catalog",
                "_id": "Q61b35YBAkHYIP5jIOWH",
                "_score": 7.6092715,
                "_source": {
                    "title_semantic": "Red shoes",
                    "title_non_semantic": "Red shoes",
                    "title_semantic_embedding": {
                        "feet": 0.85673976,
                        "dress": 0.48490667,
                        "##wear": 0.26745942,
                        "pants": 0.3588211,
                        "hats": 0.30846077,
                        ...
                    },
                    "product_id": "12345"
                }
            }
        ]
    }
}

The search successfully matched the document with Red shoes despite the query using crimson footwear, demonstrating the power of semantic search. The system automatically generated semantic embeddings for the document (truncated here for brevity) which enable these intelligent matches based on meaning rather than exact keywords.

Comparing search results

By running a similar query against the nonsemantic index title_non_semantic, you can confirm that nonsemantic fields can’t search based on context:

GET product-catalog/_search?size=1
{
  "query": {
    "match":{
      "title_non_semantic":{
        "query": "crimson footwear"
      }
    }
  }
}

The following is the search response:

{
    "took": 398,
    "timed_out": ,
    "_shards": {
        "total": 0,
        "successful": 0,
        "skipped": 0,
        "failed": 0
    },
    "hits": {
        "total": {
            "value": 0,
            "relation": "eq"
        },
        "max_score": ,
        "hits": []
    }
}

Limitations of automatic semantic enrichment

Automatic semantic search is most effective when applied to small-to-medium sized fields containing natural language content, such as movie titles, product descriptions, reviews, and summaries. Although semantic search enhances relevance for most use cases, it might not be optimal for certain scenarios:

  • Very long documents – The current sparse model processes only the first 8,192 tokens of each document for English. For multilingual documents, it’s 512 tokens. For lengthy articles, consider implementing document chunking to ensure complete content processing.
  • Log analysis workloads – Semantic enrichment significantly increases index size, which might be unnecessary for log analysis where exact matching typically suffices. The additional semantic context rarely improves log search effectiveness enough to justify the increased storage requirements.

Consider these limitations when deciding whether to implement automatic semantic enrichment for your specific use case.

Conclusion

Automatic semantic enrichment marks a significant advancement in making sophisticated search capabilities accessible to all OpenSearch Serverless users. By eliminating the traditional complexities of implementing semantic search, search developers can now enhance their search functionality with minimal effort and cost. Our feature supports multiple languages and collection types, with a pay-as-you-use pricing model that makes it economically viable for various use cases. Benchmark results are promising, particularly for English language searches, showing both improved relevance and reduced latency. However, although semantic search enhances most scenarios, certain use cases such as processing extremely long articles or log analysis might benefit from alternative approaches.

We encourage you to experiment with this feature and discover how it can optimize your search implementation so you can deliver better search experiences without the overhead of managing ML infrastructure. Check out the video and tech documentation for additional details.


About the Authors

Jon Handler is Director of Solutions Architecture for Search Services at Amazon Web Services, based in Palo Alto, CA. Jon works closely with OpenSearch and Amazon OpenSearch Service, providing help and guidance to a broad range of customers who have generative AI, search, and log analytics workloads for OpenSearch. Prior to joining AWS, Jon’s career as a software developer included four years of coding a large-scale, eCommerce search engine. Jon holds a Bachelor of the Arts from the University of Pennsylvania, and a Master of Science and a Ph. D. in Computer Science and Artificial Intelligence from Northwestern University.

Arjun Kumar Giri is a Principal Engineer at AWS working on the OpenSearch Project. He primarily works on OpenSearch’s artificial intelligence and machine learning (AI/ML) and semantic search features. He is passionate about AI, ML, and building scalable systems.

Siddhant Gupta is a Senior Product Manager (Technical) at AWS, spearheading AI innovation within the OpenSearch Project from Hyderabad, India. With a deep understanding of artificial intelligence and machine learning, Siddhant architects features that democratize advanced AI capabilities, enabling customers to harness the full potential of AI without requiring extensive technical expertise. His work seamlessly integrates cutting-edge AI technologies into scalable systems, bridging the gap between complex AI models and practical, user-friendly applications.

Create an OpenSearch dashboard with Amazon OpenSearch Service

Post Syndicated from Smita Singh original https://aws.amazon.com/blogs/big-data/create-an-opensearch-dashboard-with-amazon-opensearch-service/

Effective log analysis is essential for maintaining the health and performance of modern applications. Amazon OpenSearch Service stands out as a powerful, fully managed solution for log analytics and observability. With its advanced indexing, full-text search, and real-time analytics capabilities, OpenSearch Service makes it possible for organizations to seamlessly ingest, process, and search log data across diverse sources—including AWS services like Amazon CloudWatch, VPC Flow Logs, and more.

With OpenSearch Dashboards, you can turn indexed log data into actionable visualizations that reveal insights and help detect anomalies. By querying data stored in OpenSearch Service, you can extract relevant information and display it using a variety of visualization types—such as line charts, bar graphs, pie charts, heatmaps, and more. These tools make it effortless to monitor system behavior, spot trends, and quickly identify issues in your environment.

This post demonstrates how to harness OpenSearch Dashboards to analyze logs visually and interactively. With this solution, IT administrators, developers, and DevOps engineers can create custom dashboards to monitor system behavior, detect anomalies early, and troubleshoot issues faster through interactive charts and graphs.

Solution overview

In this post, we show how to create an index pattern in OpenSearch Dashboards, create two types of visualizations, and display these visualizations on a custom dashboard. We also demonstrate how to export and import visualizations.

Prerequisites

Before diving into log analysis with OpenSearch Dashboards, you must have the following:

  • A properly configured OpenSearch Service domain
  • A working log collection and ingestion pipeline

Amazon OpenSearch Service 101: Create your first search application with OpenSearch guides you through setting up your OpenSearch Service domain and configuring the log ingestion pipeline.

For this post, we work with the following log sources, which have already been ingested into an OpenSearch Service cluster as part of the prerequisite steps:

Access OpenSearch Dashboards

Complete the following steps to access OpenSearch Dashboards:

  1. On the OpenSearch Service console, choose Domains in the navigation pane.
  2. Check if your domain status shows as Active.
  3. Choose your domain to open the domain details page.
  4. Choose the OpenSearch Dashboards URL to open it in a new browser window.

  1. Authenticate into OpenSearch Dashboards using one of the supported methods.

Create an index pattern

After you’re logged in to OpenSearch Dashboards, you must create an index pattern. An index pattern allows OpenSearch Dashboards to locate indexes to search. Complete the following steps

  1. In OpenSearch Dashboards, expand the navigation pane and choose Dashboard Management under Management.
  2. Choose Index patterns in the navigation pane.

  1. Choose Create index pattern.
  2. For Index pattern name, enter a name (for example, log-aws-cloudtrail-*).
  3. Choose Next step.

  1. For Time field¸ choose @timestamp.
  2. Choose Create index pattern.

Create visualizations

Now that the index pattern is created, let’s create some visualizations. For this post, we create a pie chart and an area graph.

Create a pie chart

Complete the following steps to create a pie chart:

  1. In OpenSearch Dashboards, choose Visualize in the navigation pane.

  1. Choose Create visualization.

  1. Choose Pie as the visualization type.
  2. For Source¸ choose log-aws-cloudtrail-*.

  1. Under Buckets¸ choose Add and Split slices.

  1. For Aggregation, choose Terms.

  1. For Field, choose eventName.
  2. For Size, enter 10.

  1. Leave all other parameters as default and choose Update.
  2. Choose Save to save the visualization.

Sample ndjson file for the pie chart – EventNamePie.ndjson

Please refer Export and import visualizations for how to import the samples.

The following screenshot shows our pie chart, which displays different types of events and their occurrence percentage in the last 30 minutes.

Create an area graph

Complete the following steps to create an area graph:

  1. In OpenSearch Dashboards, choose Visualize in the navigation pane.
  2. Choose Create visualization.
  3. Choose Area as the visualization type.

  1. For Source¸ choose log-aws-cloudtrail-*.

  1. Under Buckets¸ choose Add and X-axis.

  1. For Aggregation, choose Date Histogram.
  2. For Field, choose @timestamp.
  3. Leave all other parameters as default and choose Update

  1. Under Advanced¸ choose Add and Split series.

  1. For Aggregation, choose Terms.
  2. For Field, choose eventName.
  3. For Size, enter 10.
  4. Leave all other parameters as default and choose Update.

  1. Choose Save.
  2. Update the time range to Last 60 minutes.
  3. Choose Refresh and Save.

The following screenshot shows an area graph with different types of events and their occurrence count in the last 60 minutes.

Sample ndjson file for Area chart – EventNameArea.ndjson

Please refer Export and import visualizations for how to import the samples.

Create a dashboard

Now we will combine the visualizations we just created into a dashboard. A dashboard serves as a customizable interface that consolidates multiple visualizations, saved searches, and various content into a comprehensive view of data. Users can combine diverse visual elements—including charts, graphs, metrics, and tables—into a single cohesive display that can be arranged and resized on a flexible grid layout. You can simultaneously apply filters and time ranges across multiple visualizations, creating a coordinated analytical experience. Complete the following steps to create a dashboard:

  1. In OpenSearch Dashboards, choose Dashboards in the navigation pane.
  2. Choose Create new dashboard.

  1. Choose Add on the menu bar.

  1. Search for and choose the visualizations you created.

You can resize panels by dragging their corners to adjust dimensions. To modify the layout arrangement, you can drag the top portion of panels, which allows you to organize them horizontally in a row formation. When working with tabular visualizations, the system provides a convenient option to export your results in CSV format for further analysis or reporting purposes.

  1. Choose Save.
  2. Change the time range to Last 60 minutes.
  3. Choose Refresh and Save.

Sample ndjson file for dashboard – CloudTrailSummary.ndjson

Please refer Export and import visualizations for how to import the samples.

The following screenshot shows the CloudTrail dashboard displaying both visualizations.

Export and import visualizations

In OpenSearch, an NDJSON file is used to import and export saved objects, such as dashboards, visualizations, maps, and index template. The NDJSON file provides a streamlined approach for handling large datasets by representing each JSON object on a separate line. This format enables efficient import/export operations, simplified data migration between environments, and seamless sharing of complex dashboard configurations. Organizations can back up and restore critical visualizations, saved searches, and dashboard settings while maintaining their integrity. The format’s structure reduces memory overhead during large transfers and improves processing speed for bulk operations. NDJSON’s human-readable nature also facilitates troubleshooting and manual editing when necessary, making it an invaluable tool for maintaining OpenSearch Dashboards deployments across development, testing, and production environments.

Export a visualization

Complete the following steps to export a visualization:

  1. In OpenSearch Dashboards, choose Saved objects in the navigation pane.
  2. Search for and select your object (in this case, a visualization), then choose Export.

The NDJSON file is downloaded in your local host.

Import a visualization

Complete the following steps to import a visualization:

  1. In OpenSearch Dashboards, choose Saved objects in the navigation pane.
  2. Choose Import.
  3. Choose the first NDJSON file to be imported from your local host.
  4. Select Create new objects with random IDs.
  5. Choose Import.

  1. Choose Done.

  1. Choose Import.

You can now open the imported object.

The following screenshot shows our updated dashboard.

Clean up

To clean up your resources, delete the OpenSearch Service domain and relevant information stored or visualizations created on the domain. You will not be able to recover the data after you delete it.

  1. On the OpenSearch Service console, choose Domains in the navigation pane.
  2. Select the domain you created and choose Delete.

Conclusion

OpenSearch Dashboards is a powerful tool for transforming raw log data into actionable visualizations that drive insights and decision-making. In this post, we’ve shown how to create visualizations like pie charts and area graphs, build comprehensive dashboards, and efficiently export and import your work using NDJSON files. By using the fully managed OpenSearch Service features, organizations can focus on extracting valuable insights rather than managing infrastructure, ultimately enhancing their observability posture and operational efficiency.

To further enhance your OpenSearch proficiency, consider exploring advanced visualization options such as heat maps, gauge charts, and geographic maps that can represent your data in more specialized ways. Implementing automated alerting based on predefined thresholds will help you proactively identify anomalies before they become critical issues. You can also use OpenSearch’s powerful machine learning capabilities for sophisticated anomaly detection and predictive analytics to gain deeper insights from your log data. As your implementation grows, customizing security settings with fine-grained access controls will provide appropriate data visibility across different teams in your organization.

For comprehensive learning resources, refer to the Amazon OpenSearch Service Developer Guide, watch Create your first OpenSearch Dashboard on YouTube, explore best practices in Amazon OpenSearch blog posts, and gain hands-on experience through workshops available in AWS Workshops.


About the Authors

Smita Singh is a Senior Solutions Architect at AWS. She focuses on defining technical strategic vision and works on architecture, design, and implementation of modern, scalable platforms for large-scale global enterprises and SaaS providers. She is a data, analytics, and generative AI enthusiast and is passionate about building innovative, highly scalable, resilient, fault-tolerant, self-healing, multi-tenant platform solutions and accelerators.

Dipayan Sarkar is a Specialist Solutions Architect for Analytics at AWS, where he helps customers modernize their data platform using AWS analytics services. He works with customers to design and build analytics solutions, enabling businesses to make data-driven decisions.

Build a multi-tenant healthcare system with Amazon OpenSearch Service

Post Syndicated from Ezat Karimi original https://aws.amazon.com/blogs/big-data/build-a-multi-tenant-healthcare-system-with-amazon-opensearch-service/

Healthcare systems face significant challenges managing vast amounts of data while maintaining regulatory compliance, security, and performance. This post explores strategies for implementing a multi-tenant healthcare system using Amazon OpenSearch Service.

In this context, tenants are distinct healthcare entities, sharing a common platform while maintaining isolated data environments. Hospital departments (like emergency, radiology, or patient care), clinics, insurance providers, laboratories, and research institutions are examples of these tenants.

In this post, we address common multi-tenancy challenges and provide actionable solutions for security, tenant isolation, workload management, and cost optimization across diverse healthcare tenants.

Understanding multi-tenant healthcare systems

Tenants in healthcare systems are diverse and have distinct requirements. For example, emergency departments need round-the-clock high availability with subsecond response times for patient care, along with strict access controls for sensitive trauma data. Research departments run complex, resource-intensive queries that are less time-sensitive but require robust anonymization protocols to maintain HIPAA compliance when working with patient data. Outpatient clinics operate during business hours with predictable usage patterns and moderate performance requirements. Administrative systems focus on financial data with scheduled batch processing and require access to billing information and insurance details only. Specialty departments like radiology and cardiology have unique requirements specific to the tasks they perform. For example, radiology requires high storage capacity and bandwidth for large medical imaging files, along with specialized indexing for metadata searches.

Understanding tenant requirements is essential for designing an effective multi-tenant architecture that balances resource sharing with appropriate isolation while maintaining regulatory compliance.

Isolation models

OpenSearch’s hierarchical structure consists of four main levels. At the top level is the domain, which contains one or more nodes that store and search data. Within the domain, indexes contain documents and define how they are stored and searched. Documents are individual records or data entries stored within an index, and each document consists of fields, which are individual data elements with specific data types and values.

Indexes include mappings and settings. Mappings define the schema of documents within an index, specifying field names and their data types. Settings configure various operational aspects of an index, such as the number of primary shards and replica shards.

The isolation model in a multi-tenant OpenSearch system can be at domain, index, or document level. The model you select for your multi-tenant healthcare system impacts security, performance, and cost. For healthcare organizations, as depicted in the following diagram, a hybrid approach typically works best, matching isolation levels to tenant requirements.

Multi-Tenancy Isolation Models

Multi-Tenancy Isolation Models

For emergency units, consider domain-based isolation, providing maximum separation by deploying separate OpenSearch domains for each tenant. Although it’s more expensive, it reduces resource contention and provides consistent performance for critical systems. This isolation simplifies compliance by physically separating sensitive patient data.

Similarly, for clinical research tenants, consider domain-based isolation despite its higher cost. Given the resource-intensive nature of research workloads—particularly genomics and population health analytics that process terabytes of data with complex algorithms—separate domains prevent these demanding operations from impacting other tenants.

For specialty departments like cardiology or radiology, where workload patterns are similar but data access patterns are distinct, index-based isolation is a good fit. These departments share a domain but maintain separate indexes. This approach provides strong logical separation while allowing more efficient resource utilization.

For administrative departments where data is less sensitive, a document-based isolation is sufficient, and multiple tenants can share the same indexes.

Data modeling

Effective data modeling is crucial for maintaining performance and manageability in a multi-tenant healthcare system. Implement a consistent index naming convention that incorporates tenant identifiers, data categories, and time periods like {tenant-id}-{data-type}-{time-period}. Tenant-id identifies the entity, for example, cardiology. Examples of the indexes are cardiology-ecg-202505 or radiology-mri-202505. This structured approach simplifies data management, access control, and lifecycle policies.

Consider data access patterns when designing your index strategy. For example, for time-series data like vital signs or telemetry readings, time-based indexes with appropriate rotation policies will improve performance and simplify data lifecycle management.

For shared indexes using document-based isolation, make sure tenant identifiers are consistently applied and indexed for efficient tenant-based filtering.

Tenant management

Effective tenant management prevents resource contention and provides consistent performance across your healthcare system. Implement a hybrid isolation model using a tenant tiering framework based on criticality. The following table outlines the tiering framework.

Tier Tenant Type SLA Resources Operational Limits Behavior
Tier-1 Critical

Emergency departments

ICU/Critical care

Operating rooms

24/7 SLA 99.99%

Sub-second response

RPO: Near zero

RTO: Less than 15 minutes

Guaranteed 50% CPU, 50% memory

Dedicated hot nodes

2 replicas minimum

100 concurrent requests

20 MB request size

30-second timeout

No throttling

Priority query routing

Preemptive scaling

Automatic failover

Tier-2 Urgent

Inpatient units

Specialty departments

Radiology/imaging

24/7 SLA with 99.9% availability

Less than 2-second response time

RPO: Less than 15 minutes

RTO: Less than 1 hour

Guaranteed 30% CPU, 30% memory

Shared hot nodes

1–2 replicas

50 concurrent requests

15 MB request size 60-second timeout

Limited throttling during peak

High-priority query routing

Automatic scaling

Automated recovery

Tier-3 Standard

Outpatient clinics

Primary care

Pharmacy

Laboratory

Business hours SLA (8 AM – 8 PM)

99.5% availability Less than 5-second response time

RPO: Less than 1 hour

RTO: Less than 4 hours

Guaranteed 15% CPU, 15% memory

Shared nodes

1 replica

25 concurrent requests

10 MB request size

120-second timeout

Moderate throttling

Standard query routing

Fair thread allocation

Manual scaling

Business hours optimization

Tier-4 Research

Clinical research

Genomics

Population health

Best-effort

SLA, up to 99% availability

Less than 30-second response time

RPO: Less than 24 hours

RTO:  Less than 24 hours

Guaranteed 5% CPU, 10% memory

Burst capacity during off-hours

0–1 replicas

10 concurrent requests

50 MB request size

300-second timeout

Aggressive throttling during pea

Compute optimized instances

Large heap size

Research-specific plugins

Tier-5 Admin

Billing/finance

HR systems

Inventory management

Business hours SLA (9 AM – 5 PM) 99% availability Less than 10-second response time

RPO: Less than 24 hours

RTO: Less than 48 hours

No guaranteed resources

Burstable capacity

UltraWarm for historical

1 replica

5 concurrent requests

5 MB request size

180-second timeout

Aggressive throttling

Lowest priority query routing

Batch processing preferred

Off-hours scheduling

Cost-optimized storage

Workload management

When you use OpenSearch Service for multi-tenancy, you must balance your tenants’ workloads to make sure you deliver the resources needed for each to ingest, store, and query their data effectively. A multi-layered workload management framework with a rule-based proxy and OpenSearch Service workload management can effectively address these challenges. For details, see this blog post: Workload management in OpenSearch-based multi-tenant centralized logging platforms.

Security framework

Healthcare data requires protection due to its sensitive nature and regulatory requirements. The OpenSearch Service security framework is specifically adaptable to healthcare’s strict security requirements. This framework combines multiple layers of access control, captured in the following diagram.

Multi-tenancy fine-grained access control in Amazon OpenSearch Service

Multi-tenancy fine-grained access control in Amazon OpenSearch Service

An important step in this framework is role mapping, where AWS Identity and Access Management (IAM) roles are mapped to OpenSearch roles for role-based access control (RBAC). For example, emergency departments can implement the ED-Physician role with access to patient history across departments, and the ED-Staff role with access to vital sign and medication data. You can map emergency department roles to OpenSearch roles.

With document-level security (DLS), you can limit emergency department staff to active emergency patients only while restricting access to discharged patient data only to the providers who treat them. With field-level security (FLS), you can allow access to medical fields while masking billing and insurance data. You can also provide attribute-based access control (ABAC) policies to allow access based on patient status.

For research departments, you can create Clinical-Researcher roles with read-only access to datasets. Integrate academic roles to research roles to make sure researchers only access data for studies they’re authorized to conduct. For DLS, implement filters to make sure researchers only access approved documents. Use FLS to anonymize HIPAA identifiers. For research departments, ABAC should evaluate the study phase and researcher’s location.

For outpatient care, you can define Medical-Provider roles with full access to assigned patients’ records and Medical-Assistant roles limited to documenting vitals and preliminary information. For DLS, limit access to patient’s physicians only. For FLS, restrict access to medical data only, while limiting nurses to demographic, vital signs, and medication fields. Implement time-aware ABAC policies that restrict access to patient records outside of business hours unless the provider is on-call.

For administrative departments, you can implement Financial roles with access to charge codes and insurance information but no clinical data. For DLS, make sure financial staff only access billing documents. FLS provides access to billing codes, dates of service, and insurance fields while masking clinical content.

For specialty departments, you can create technician roles like Radiologist and apply DLS filters restricting access to the data to these roles and referring physician. FLS allows technicians to see clinical history and previous findings specific to their specialty.

Enable comprehensive audit logging to track access to protected health information. Configure these logs to capture user identity, accessed data, timestamp, and access context. These audit trails are essential for regulatory compliance and security investigations.

Managing data lifecycle for compliance

Index State Management (ISM) capabilities combined with OpenSearch Service storage tiering enable an elaborate approach to data lifecycle management that can be tailored to diverse tenant needs. ISM provides a robust way to automate the lifecycle of indexes by defining policies that dictate transitions between Hot, UltraWarm, and Cold storage tiers based on criteria like index age or size. This automation can extend to the archive tier by creating snapshots, which are stored in Amazon Simple Storage Service (Amazon S3) and can be further transitioned to Amazon S3 Glacier or Glacier Deep Archive for long-term, cost-effective archiving of data that is rarely accessed.

Frame your ISM policy along the following guidelines:

Keep critical patient data in hot storage for 180 days to support immediate access. Transition to warm storage for the next 12 months, then move to cold storage for years 2–7. After 7 years, archive records.

For research data benefits, use project-based lifecycle policies rather than strictly time-based transitions. Maintain research datasets in hot storage during active project phases, regardless of data age. When projects conclude, transition data to warm storage for 12 months. Move to cold storage for the following 5–10 years based on research significance. Afterward, archive records.

For outpatient clinic data, keep recent patient records in hot storage for 90 days, aligning index rollover with typical follow-up windows. Transition to warm storage for months 4–18, coinciding with common annual visit patterns. Move to cold storage for years 2–7. Archive after 7 years.

For administrative data, maintain current fiscal year data in hot storage with automated transitions at year-end boundaries. Move previous fiscal year data to warm storage for 18 months to support auditing and reporting. Transition to cold storage for years 3–7. Archive financial records after 7 years.

For the specialty department data, keep recent metadata in hot storage for 90 days while moving large files, like images, to warm storage after 30 days. Transition complete records to cold storage after 18 months. Archive after 7 years.

Cost management and optimization

Healthcare organizations must balance performance requirements with budget constraints. Effective cost management strategies are essential for sustainable operations.

Implement comprehensive tagging strategies that mirror your index naming conventions to create a unified approach to resource management and cost tracking. Like the index naming convention, design your tags to identify the tenant, application, and data type (for example, “tenant=cardiology” or “application=ecg“). These tags, combined with AWS Cost Explorer, provide visibility into expenses across organizational boundaries.

Develop cost allocation mechanisms that fairly distribute expenses across different tenants. Consider implementing tiered pricing structures based on data volume, query complexity, and service-level guarantees. This approach aligns costs with value and encourages efficient resource utilization.

Optimize your infrastructure based on tenant-specific metrics and usage patterns. Monitor document counts, indexing rates, and query patterns to right-size your clusters and node types. Use different instance types for different workloads—for example, use compute-optimized instances for query-intensive applications.

Use OpenSearch Service storage tiering to optimize costs. UltraWarm provides significant cost savings for infrequently accessed data while maintaining reasonable query performance. Cold storage offers even greater savings for data that’s rarely accessed but must be retained for compliance purposes.

Conclusion

Building a multi-tenant healthcare system on OpenSearch Service requires careful planning and implementation. By addressing tenant isolation, security, data lifecycle management, workload control, and cost optimization, you can create a platform that delivers improved operational efficiency while maintaining strict compliance with healthcare regulations.


About the Authors

Ezat Karimi is a Senior Solutions Architect at AWS, based in Austin, TX. Ezat specializes in designing and delivering modernization solutions and strategies for database applications. Working closely with multiple AWS teams, Ezat helps customers migrate their database workloads to the AWS Cloud.

Jon Handler is a Senior Principal Solutions Architect at Amazon Web Services based in Palo Alto, CA. Jon works closely with OpenSearch and Amazon OpenSearch Service, providing help and guidance to a broad range of customers who have vector, search, and log analytics workloads that they want to move to the AWS Cloud. Prior to joining AWS, Jon’s career as a software developer included 4 years of coding a large-scale, ecommerce search engine. Jon holds a Bachelor’s of the Arts from the University of Pennsylvania, and a Master’s of Science and a PhD in Computer Science and Artificial Intelligence from Northwestern University.

Trusted identity propagation using IAM Identity Center for Amazon OpenSearch Service

Post Syndicated from Sohaib Katariwala original https://aws.amazon.com/blogs/big-data/trusted-identity-propagation-using-iam-identity-center-for-amazon-opensearch-service/

Enterprise customers of Amazon OpenSearch Service require comprehensive security controls with seamless authentication and authorization mechanisms when accessing data in provisioned domains and Amazon OpenSearch Serverless collections. Security teams within these organizations must not only maintain compliance with enterprise policies but also need to make sure that their users can access data securely, with robust identity management. AWS IAM Identity Center is a popular mechanism for identity management that provides single sign-on (SSO) capabilities for these enterprise customers. IAM Identity Center can use Security Assertion Markup Language (SAML) with both OpenSearch Service provisioned domains and OpenSearch Serverless. Now, by using trusted identity propagation, IAM Identity Center provides a new, direct method for accessing data in OpenSearch Service.

In this post, we outline how you can take advantage of this new access method to simplify data access using the OpenSearch UI and still maintain robust role-based access control for your OpenSearch data.

Trusted identity propagation overview

Trusted identity propagation in IAM Identity Center adds the identity context of a user to a role when accessing OpenSearch Service, which in turn uses this context to authorize and scope OpenSearch data access. This simplifies the authentication and authorization flow for customers because the applications access the data on their behalf. Users or user agents need not be present between the application and the backend services for this authorization to happen, unlike methods like SAML where a user agent needs to be present between these entities as a go-between for exchanging assertions. This flexibility helps simplify accessing a wide variety of data sources such as data residing within the Amazon Virtual Private Cloud (Amazon VPC) of an OpenSearch Service domain, or an OpenSearch Serverless collection. By using the OpenSearch UI, you can additionally simplify the backend connections, resulting in seamless access to the data. The following figures shows how the identity propagation works with OpenSearch Service.

Prerequisites

Before starting to use IAM Identity Center with OpenSearch Service, there are a few options that you must enable. To start, set up an organization or account instance of IAM Identity Center following the instruction in this guide. For OpenSearch Service-provisioned domains, you must enable the IAM Identity Center (IDC) Authentication –new option. You can do this though AWS CloudFormation, OpenSearch REST API, AWS SDK, or the AWS Management Console.

To enable Identity Center using the console

  1. To add the capability for an existing provisioned domain, go to the OpenSearch Service console and navigate to the Security configuration tab and choose Edit.

Amazon OpenSearch Service console highlighting security settings, cluster health status, and VPC endpoint configuration

  1. After this step, or if you are creating new domain, select the check box for IAM Identity Center (IDC) Authentication – new.
  2. You have various options to choose for Subject Key and Roles Key depending upon how you want to establish your role-based access control discussed later in this post. For now, select UserName for Subject Key and GroupName for Roles Key.

AWS IAM Identity Center SSO configuration interface with API authentication controls and identity mapping settings

  1. For OpenSearch Serverless, choose Serverless in the navigation pane, then Security and Authentication. Choose Edit in the IAM Identity Center (IdC) authentication – new section.

AWS OpenSearch Service authentication management console with SAML providers list and IAM Identity Center integration status

  1. Select the checkbox for Authenticate with IAM Identity Center, and then choose Save.

AWS IAM Identity Center configuration modal for enabling centralized authentication and resource access management

  1. Select the checkbox for Authentication with IAM Identity Center under Single sign-on authentication, when creating an OpenSearch UI application. For step-by-step instructions on how to create an OpenSearch UI application, see Creating an OpenSearch UI application

AWS single sign-on setup interface with option to enable IAM Identity Center for unified access management

After these steps, you’re ready to configure IAM Identity Center by creating new users and groups, or by using existing user identities.

Propagating IAM Identity Center identities

Currently, adding single sign-on authentication with IAM Identity Center can be done while setting up a new OpenSearch UI application. Use the following steps to create a new OpenSearch UI application. Note that single sign-on currently cannot be turned on after an application is created. After single sign-on is enabled, you should see an AWS managed application under Applications in the Identity Center console.

AWS Identity Center interface showing managed applications tab with OpenSearch integration and service details

Assigning users and groups

After the application is created and the status shows as Active, you need to assign users and groups to the application. This assignment is important and recommended because these assignments determine the scope and permissions for data access within OpenSearch Service. To do this, select the application you created in the previous steps in the OpenSearch Service console. Here, you will see an option for IAM Identity Center user and groups under Single sign-on authentication. Choose Assign users and groups and select the appropriate Identity Center users and groups.

 AWS IAM Identity Center dashboard showing connected status, role details, and option to assign users and groups for SSO

For OpenSearch Serverless, you must create a new data access policy or add a rule to an existing one to grant IAM Identity Center principals appropriate permissions to access the collections. For example, the following figure shows a data access policy that grants specific permissions to a one user with Rule 1 and provide a more restrictive permission to a group with Rule 2.

Amazon OpenSearch Service console displaying sample data access policy with IAM principal and collection/index permissions

At this point your OpenSearch Service domains, OpenSearch Serverless collections and OpenSearch UI are set up for identity propagation.

Fine grained access control for IAM Identity Center identities

Fine grained access control is a role-based access control for OpenSearch Service that provides security at index, document, and field levels for provisioned domains. You can choose what aspects of identity context you propagate to OpenSearch Service. You can choose between UserId, UserName, and Email for your Subject keys, and GroupId and GroupName for your Roles key. This configuration is important because the values of the properties in the identity context are used to match exactly with the user and backend role mapping within OpenSearch Service provisioned domains. Note that if IAM Identity Center sign-on isn’t enabled, OpenSearch Service can only evaluate the request signature with AWS signature Version 4. This means that the role your OpenSearch UI will use won’t contain identity context for authorization. To complete authorization, add the values of the identity context fields to the OpenSearch role mapping. See Mapping roles to users under Managing permissions. Role mapping can be done using OpenSearch REST API, AWS SDK, or using OpenSearch Dashboards.

To map roles using OpenSearch Dashboards

  1. From the menu icon  on the top left corner or your screen, select Management, Security, Roles, <Your role>.
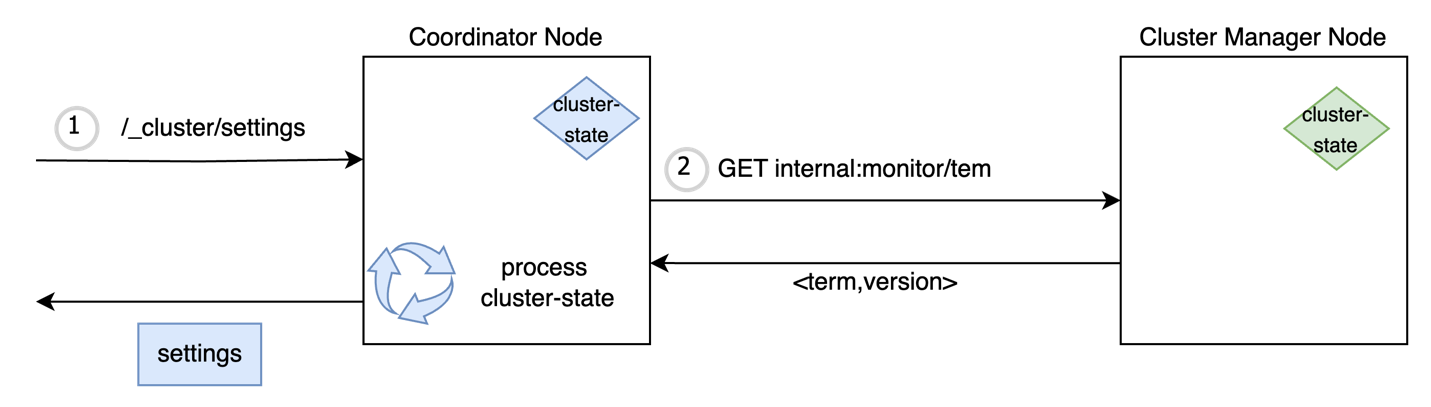
  2. Choose the Mapped Users tab and select Manage mapping.

AWS security console showing Map User interface with internal user creation and backend role management for IAM

  1. When mapping the role, make sure that you enter the values corresponding to the Subject key. This value must be the same as in your identity context. Additionally, use the Roles key to assign access-based IAM Identity Center groups.

With OpenSearch Serverless, the granularity of access control is at the index level so you will need to add additional rules in the Data Access Policy to control principals who can access collections or indices within a collection.

Verifying identity propagation

The final step is to verify identity propagation.

  1. Open the OpenSearch UI application and select IAM Identity Center from the Login drop down.

  1. After you complete the login process with IAM Identity Center, the OpenSearch UI will open. Choose the user icon in the lower left corner of the screen to verify that it’s your correct principal from Identity Center. It should match the Identity Center property you chose earlier.
OpenSearch welcome interface showing available workspaces, documentation links, and user profile menu with logout option

  1. To verify correct identity propagation, choose the Dev tools  icon just above the user profile icon in the bottom left corner of the screen.
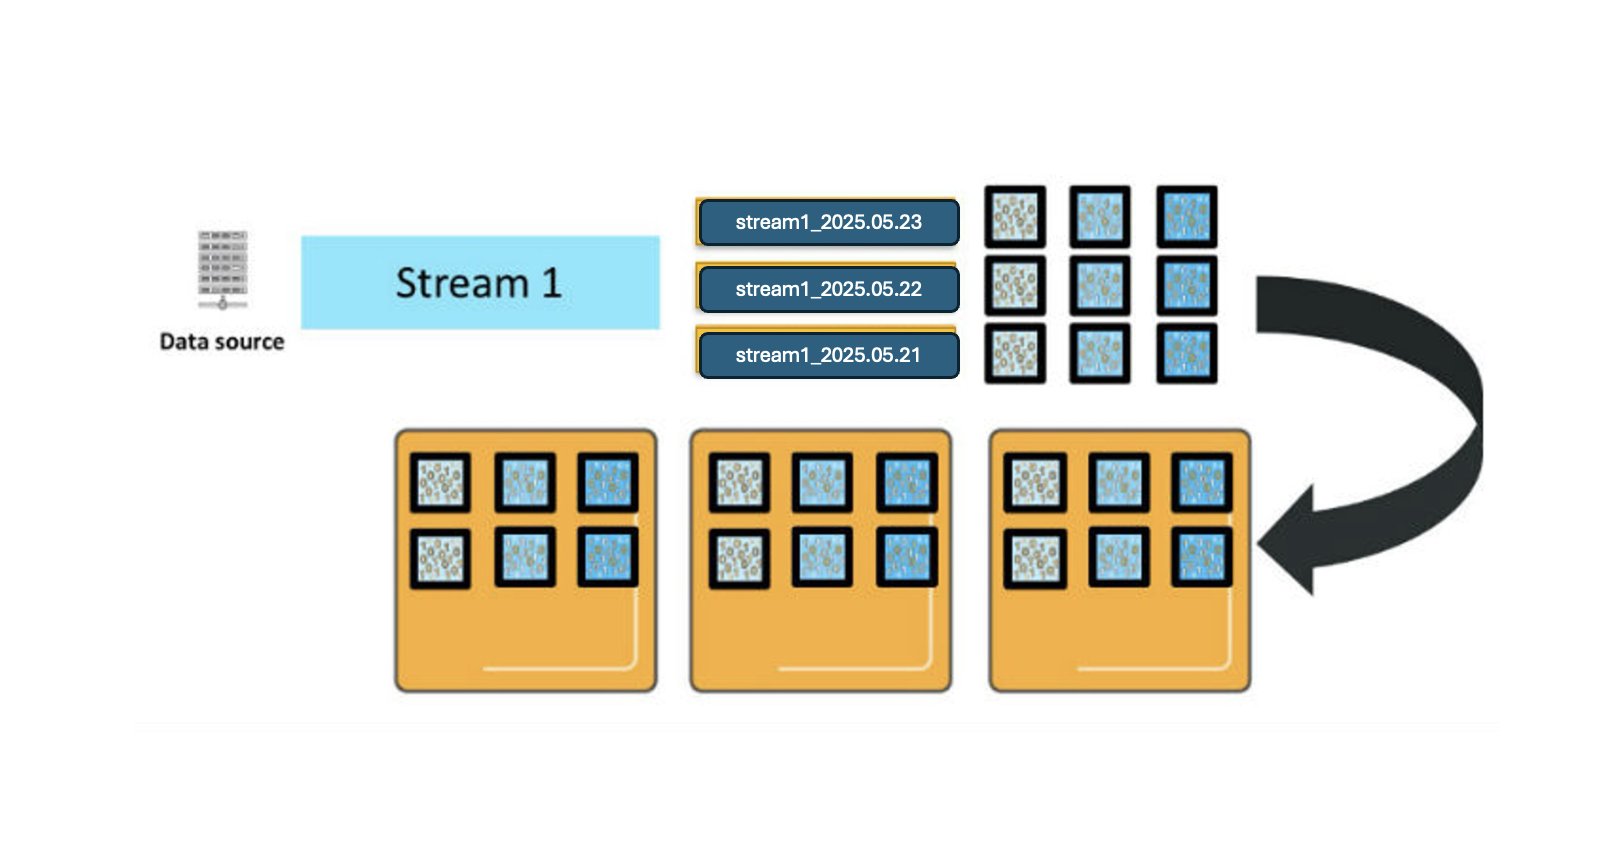
  2. Select the correct OpenSearch domain or OpenSearch Serverless collection data source in the top right corner of the screen and run a _search query. You should see results from the data source confirming that the identity is correctly propagated to OpenSearch Service.
Dev tools showing successful search operation with 5ms response time and config details

Conclusion

In this post, we showed you how to use Trusted Identity Propagation using IAM Identity Center for Amazon OpenSearch Service, providing a streamlined approach to secure data access while maintaining robust access controls. This solution offers several key benefits:

  • Simplified authentication: By eliminating the need for user agents between applications and backend services, the solution streamlines the authentication process compared to traditional SAML-based approaches.
  • Enhanced security: The integration maintains comprehensive security controls while providing seamless authentication and authorization mechanisms for both OpenSearch Service provisioned domains and Amazon OpenSearch Serverless collections.
  • Flexible identity management: Organizations can use existing IAM Identity Center implementations to manage user access, making it easier to maintain compliance with enterprise security policies.
  • Fine-grained access control: The solution supports detailed access control at the index, document, and field level for provisioned domains, allowing organizations to implement precise security measures.

Get started implementing this solution in your environment today!

For more information about identity management and security best practices with OpenSearch Service, we recommend:


About the authors

Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

Sohaib Katariwala is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service based out of Chicago, IL. His interests are in all things data and analytics. More specifically he loves to help customers use AI in their data strategy to solve modern day challenges.