Tag Archives: Architecture

How Flutter UKI optimizes data pipelines with AWS Managed Workflows for Apache Airflow

Post Syndicated from Monica Cujerean, Ionut Hedesiu original https://aws.amazon.com/blogs/big-data/how-flutter-uki-optimizes-data-pipelines-with-aws-managed-workflows-for-apache-airflow/

This post is co-written with Monica Cujerean and Ionut Hedesiu from Flutter UKI.

In this post, we share how Flutter UKI transitioned from a monolithic Amazon Elastic Compute Cloud (Amazon EC2)-based Airflow setup to a scalable and optimized Amazon Managed Workflows for Apache Airflow (Amazon MWAA) architecture using features like Kubernetes Pod Operator, continuous integration and delivery (CI/CD) integration, and performance optimization techniques.

About Flutter UKI

As a division of Flutter Entertainment, Flutter UKI stands at the forefront of the sports betting and gaming industry. Flutter UKI offers a diverse portfolio of entertainment options, encompassing sports wagering, casino games, bingo, and poker experiences. Flutter UKI’s digital presence is robust, operating through an array of renowned online brands. These include the iconic Paddy Power, Sky Betting and Gaming, and Tombola. While Flutter UKI has established a strong online foothold, it maintains a significant physical presence with a network of 576 Paddy Power betting shops strategically located across the United Kingdom and Ireland.

The Data team at Flutter UKI is integral to the company’s mission of using data to drive business success and innovation. Specializing in data, their teams are dedicated to ensuring the seamless integration, management, and accessibility of data across multiple facets of the organization. By developing robust data pipelines and maintaining high data quality standards, Flutter UKI empowers stakeholders with reliable insights, optimizes operational efficiencies, and enhances the user experience. Its commitment to data excellence underpins its efforts to remain at the forefront of the online gaming and entertainment industry, delivering value and strategic advantage to the business.

The journey from self managing Airflow on Amazon EC2 to operating Airflow workloads at scale using Amazon MWAA

Flutter UKI’s data orchestration story began in 2017 with a modest Apache Airflow deployment on EC2 instances. As the company’s digital footprint expanded, so did their data pipeline requirements, leading to an increasingly complex monolithic cluster that demanded constant attention and resource scaling. The operational overhead of managing these EC2 instances became a significant challenge for their engineering teams. In 2022, Flutter UKI reached a crossroads. They needed to choose between re-architecting their service on Amazon Elastic Kubernetes Service (Amazon EKS) or embracing Amazon Managed Workflows for Apache Airflow (MWAA).

Flutter UKI was looking to transform their data orchestration service from a resource-intensive, self-managed system to a more efficient, managed service that would allow them to focus on their core business objectives rather than infrastructure management. Through extensive proof-of-concept (POC) testing and close collaboration with AWS Enterprise Support, Flutter UKI gained confidence in the ability of Amazon MWAA to handle their sophisticated workloads at scale. Their choice of MWAA over a self-managed solution on Amazon EKS reflected Flutter UKI’s strategic focus on using managed services to reduce operational complexity and accelerate innovation.

The migration to Amazon MWAA followed a methodical approach. There was extensive testing of multiple POCs. During the POCs, the engineering team found MWAA to have a good ease of use, which helped them reduce the learning curve resulting in faster. Learning from each POC, they iterated on the final architecture by making data-driven decisions. Starting with a small subset of directed acyclic graphs (DAG), the Flutter UKI team expanded their deployment over time, gradually moving hundreds and eventually thousands of workflows to the managed service. This careful, phased transition allowed them to validate the performance and reliability of MWAA while minimizing operational risk.

High-level architecture design

During the service re-architecture, the data team strategically managed over 3,500 dynamically generated DAGs by implementing a sophisticated distribution approach across multiple Amazon MWAA environments to create a workload isolated environment. Another reason for having multiple environments was to make sure that no one MWAA environment doesn’t get overloaded by multiple DAGs. By placing DAG files across diverse Amazon Simple Storage Service (Amazon S3) locations and configuring unique DAG_FOLDER paths for each environment, the data team created an intelligent load balancing mechanism that allocates workflows based on complex criteria including environment type, task volume, and environment-specific DAG affinity. A round-robin distribution strategy was designed to minimize single environment load, ensuring scalable infrastructure with zero performance degradation. This approach allowed the team to optimize workflow orchestration, maintaining high performance while efficiently managing an extensive collection of dynamically generated DAGs across multiple MWAA environments. To provide more compute to individual tasks and to keep the MWAA efficient, Flutter UKI delegated the DAG execution to an external compute environment using Amazon Elastic Kubernetes Service (Amazon EKS). The resulting high-level architecture is shown in the following figure.

  1. Kubernetes Pod Operator (KPO) for tasks: Flutter UKI transitioned from using custom operators and many native Airflow operators to exclusively utilizing the Kubernetes Pod Operator (KPO). This decision simplified their architecture by eliminating unnecessary complexity, reducing maintenance overhead, and mitigating potential bugs. Additionally, this approach enabled them to allocate compute resources on a per-task basis, optimizing overall service performance. It also enabled the use of different container images for different tasks, thereby avoiding library dependency conflicts.
  2. Kubernetes Pod Operator wrapper (KPOw): Instead of using KPO directly, they developed a wrapper (KPOw) around it. This wrapper abstracts the underlying complexity and minimizes the impact of signature changes in Airflow, Amazon MWAA, Amazon EKS, or operator versions. By centralizing these changes, they only need to update the wrapper rather than thousands of individual DAGs. The wrapper also simplifies DAGs by hiding repetitive parameters, such as node affinity, pod resources, and EKS cluster configurations. Furthermore, it enforces company-specific naming conventions and allows for parameter validation at task execution time rather than during DagBag refresh. They also introduced profiles and image files, where profile files contain necessary KPO parameters, and the corresponding image files link to the repository for the task’s container image. This setup ensures consistency across tasks using the same profile and facilitates simultaneous updates across tasks.
  3. Monthly image updates in Kubernetes: Enforcing a policy of monthly image updates made sure that their code remained current, preventing security vulnerabilities and avoiding extensive code changes due to deprecated libraries.
  4. Continuous Airflow updates: Flutter UKI maintains a cutting-edge infrastructure by implementing new Airflow versions shortly after release, while following a carefully orchestrated deployment strategy. Their approach uses standard Amazon MWAA configurations and employs a systematic testing protocol. New versions are first deployed to development and test environments for thorough validation before reaching production systems. This methodical progression significantly reduces the risk of disruptions to business-critical workflows.

To achieve operational excellence, Flutter UKI has implemented a comprehensive monitoring framework centered on Amazon CloudWatch metrics. Their monitoring solution includes strategically configured alarms that provide early warning signals for potential issues. This proactive monitoring approach enables their teams to quickly identify and investigate anomalies in production workload executions, ensuring high availability and performance of their data pipelines. The combination of careful version management and robust monitoring exemplifies Flutter UKI’s commitment to operational excellence in their cloud infrastructure.

  1. CI/CD integration: By managing their code in GitLab, with mandatory code reviews and using Argo Events and Argo Workflows for image updates in AWS ECR, they streamlined their development processes.
  2. Performance Optimization: A significant portion of the DAGs are dynamically generated based on database metadata. This generation process runs outside Amazon MWAA, with its own CI/CD pipeline, and the resulting DAG files are stored in the S3 DAG. Placing code outside of tasks was avoided, including parameter evaluation. Parameters and secrets are stored in AWS Secrets Manager and retrieved at task runtime. Engineers aim to minimize or eliminate inter-service dependencies within MWAA.

DAGs are scheduled to distribute execution times as evenly as possible. Task code and common modules are hosted on Amazon S3 and retrieved at runtime. For larger codebases, Amazon Elastic File System (Amazon EFS) volumes are mounted to task pods are used.

Results

Today, Flutter UKI’s infrastructure comprises four Amazon MWAA clusters, each executing tasks on dedicated Amazon EKS node groups. They manage approximately 5,500 DAGs encompassing over 30,000 tasks, handling more than 60,000 DAG runs daily with a concurrency exceeding 450 tasks running simultaneously across clusters. They anticipate a 10% monthly increase in this workload in the short to medium term. During major events like Cheltenham and Grand National, where data load increases by 30%, their MWAA service has demonstrated stability and scalability, achieving a 100% success rate for critical processes in 2025, a significant improvement over previous years.

Conclusion

Flutter UKI’s journey with AWS Managed Workflows for Apache Airflow (Amazon MWAA) has resulted in a stable, scalable, and resilient production environment. The careful re-architecting of Flutter UKI’s service, combined with strategic decisions around task execution and infrastructure management, has not only simplified their operations, but also enhanced performance and reliability. Security and compliance benefits were also noticed, because MWAA provides managed security updates, built-in encryption, and integration with AWS security services. Perhaps most importantly, the shift to MWAA has allowed Flutter UKI’s engineering teams to redirect their efforts from infrastructure maintenance to business-critical tasks, focusing on DAG development and improving data pipeline efficiency, ultimately accelerating innovation in their core business operations.

If you’re looking to reduce operational overhead and migrate to a fully managed Airflow solution on AWS, consider using Amazon MWAA. Get in touch with your Technical Account Manager or your Solutions Architect to discuss a solution specific to your use-case. You can also reach out to AWS Support by creating a case if you’re facing an issues setting up the service.

Ready to see what Amazon MWAA is like? Visit the AWS Management Console for Amazon MWAA. For more information, see What Is Amazon Managed Workflows for Apache Airflow. Additionally, Using Amazon MWAA with Amazon EKS shows you how to integrate Amazon MWAA with Amazon EKS.


About the authors

Monica Cujerean is a Principal Data Engineer at Flutter UKI, focusing on service related initiatives that cover performance optimization, cost effectiveness, and new feature adoption on most AWS service in our stack: Amazon MWAA, Amazon Redshift, Amazon Aurora, and Amazon SageMaker.

Ionut Hedesiu is a Senior Data Architect at Flutter UKI, responsible for designing strategic solutions to cover complex and varied business needs. His main expertise is on Amazon MWAA, Kubernetes, Amazon Sagemaker, and ETL solutions.

Nidhi Agrawal is a Technical Account Manager at AWS and works with large enterprise customers to provide the technical guidance, best practices, and strategic support to customers, helping them optimize their environments in the AWS Cloud.

John Kellett is a Senior Customer Solutions Manager with 25 years of experience across private and public sectors. John helps drive end-to-end customer engagement through program management excellence. By understanding and representing customers’ strategic visions, John aligns to develop the people, organizational readiness, and technology competencies to meet the desired outcomes.

Sidhanth Muralidhar is a Principal Technical Account Manager at AWS. He works with large enterprise customers who run their workloads on AWS. He is passionate about working with customers and helping them architect workloads for cost, reliability, performance, and operational excellence at scale in their cloud journey. He has a keen interest in data analytics as well.

Empower your teams with modern architecture governance

Post Syndicated from Rostislav Markov original https://aws.amazon.com/blogs/architecture/empower-your-teams-with-modern-architecture-governance/

Agile product teams thrive on autonomy and rapid iteration, especially in the cloud where they can quickly deploy and test systems. However, traditional architecture governance often stands in their way, because many enterprises still impose centralized, one-off architecture signoffs early in the process. Historically, these signoffs verified design compliance with corporate standards in a slower, on-premises world. In cloud environments, such signoffs quickly become obsolete—along with their associated architectural documents—and discourage teams from considering new insights.

Modern cloud architectures demand a new governance approach. In this post, we show how collaborative architecture oversight can transform team performance through automation, self-service platforms, and distributed decision-making. We explore how key stakeholders (developers, architects, security specialists, and shared services teams) can participate in architectural decisions through asynchronous approval workflows, while making sure non-negotiable controls such as encryption at rest and in transit are consistently enforced through automation and policy as code. This approach empowers teams to experiment and adapt quickly while maintaining robust enterprise standards.

The promise of traditional architecture signoffs

Traditional architecture governance centers around formal reviews where teams submit detailed design documents to a central architecture board. These artifacts often include comprehensive diagrams, technology selections, security plans, and integration specifications. Architects and a variety of stakeholders such as security specialists, compliance officers, quality assurance, and operations teams review these documents in scheduled meetings before issuing a signoff. These approvals represent point-in-time validations against enterprise standards, assuming minimal deviation during implementation.

Why traditional signoffs fall short

Signoffs can create challenges in modern cloud architectures:

  • Substituting for continuous compliance when automated verification is missing, creating false assurance through one-off reviews
  • Creating a restrictive “check-the-box” mentality where meeting minimum documented requirements becomes the goal instead of exploring the best solutions
  • Removing decision authority from implementation teams who often have the most contextual knowledge
  • Delaying implementation feedback loops and reducing organizational agility

Consider an agile team responsible for a strategic cloud application that’s moved beyond minimal viable product and is now scaling to support growing business demands. The system architecture must evolve to handle increasing data volumes, performance requirements, and unanticipated integrations. However, corporate stakeholders insist on rigid adherence to the originally approved architecture documents. Although governance is essential for production systems, this inflexible approach with an early architecture signoff prevents the team from implementing architectural improvements as they go. What appears as meaningful control to stakeholders becomes a stifling constraint for builders, ultimately compromising the system stability the governance process aims to protect.

Modern cloud architecture support

A modern architecture function operates around evolving capabilities across three core areas: preapproved blueprints, distributed governance, and automated insights—with traditional signoffs reserved as an exception path for unique use cases.

A modern architecture function operates around evolving capabilities across three core areas: preapproved blueprints, distributed governance, and automated insights—with traditional signoffs reserved as an exception path for unique use cases.

Preapproved blueprints

Preapproved blueprints like reference architectures and code templates enable your teams to move faster while maintaining corporate standards. This approach supports a use-case-focused assessment model, where architects can concentrate on evaluating specific workflows or threats relevant to a unique use case—rather than having to understand the entire system or threat model from scratch. In this way, the architecture function shifts to managing by exception and refocus reviews on deviations from the standard. Blueprints should have gravity, guiding teams towards standardized patterns while preventing fragmentation through too many tools, databases, middleware options, or SDKs. Consider the following:

  • Pattern-based reference architectures – These set clear principles for security and resilience without micromanaging. These standards align teams while allowing innovation within a reliable framework. The cloud-driven enterprise transformation at BMW Group exemplifies how moving from signoffs to enablement through pattern-based architectures can be successful.
  • Self-service platforms – These provide standardized resources that empower teams to build independently. A self-service platform with preapproved templates for deployment toolchains and infrastructure code enables confident and rapid development. Most companies host these on internal developer platforms like Backstage or AWS Service Catalog. This also allows controlled changes to the blueprints and to track their adoption.
  • Blueprint lifecycle – Blueprints require their own approval process. Although this creates significant efficiency by reducing individual system reviews, it introduces the challenge of managing existing deployments when patterns are updated. Include versioning and migration strategies when introducing new blueprints.

Distributed governance

Distributed governance treats architectural decision-making as a continuous, collaborative process with clear accountability, delegating decision-making and empowering your builders within established blueprints. Consider the following:

  • Architecture decision records (ADRs) – These replace formal, one-off signoffs by documenting decisions for each build iteration. This approach promotes transparency and maintains team agility without compromising accountability for decisions and approvals with key stakeholders. It also allows teams to defer decisions until they are most relevant. For practical implementation guidance, see Using architectural decision records to streamline decision-making for a software development project. To learn about how to write concise ADRs and avoid duplication, consult the ADR templates GitHub repository and When Should I Write an Architecture Decision Record.
  • Community-driven consultations – Architecture departments can foster self-organization by creating architecture communities of practice for peer knowledge-sharing. These communities enable collaboration on best practices, challenges, and standards, cultivating a culture of distributed decision-making, without eliminating the lines of responsibility and accountability for final decisions. This approach works because deep architectural expertise often resides with builders who have hands-on experience with specific use cases and technologies. The role of the architecture function shifts towards providing the necessary infrastructure and identifying thought leaders in the organization.

Automated insights

Automated insights enable compliance with corporate standards through real-time monitoring and adaptation:

Comparison

The modern view improves the overall value-add and support model of your architecture function. The following table compares the traditional and modern views.

Aspect Traditional View Modern View
Purpose Centralized signoff to enforce control and reduce risk Empower teams with preapproved standards to prevent sprawl and manage their distribution such as through Backstage
Architecture approach Fixed, one-time design Evolving, treated as a parametrized, reusable code product refined through feedback
Team empowerment Limited, decisions approved by centralized authority High, teams make decisions within clear standards
Team speed and agility Slower, due to dependency on signoff Faster, continuous iteration without waiting for approvals
Risk management Early signoff to lock in decisions and reduce uncertainty Risk managed through continuous control validation with automated evidence collection, providing stronger assurance for second and third lines of defense than point-in-time assessments
Compliance Manual checks by experts Automated through policy as code and AI tools
Transparency Limited, focused on approval documentation High, lightweight decision records for technical stakeholders and visualizations or dashboards for non-technical oversight functions
Collaboration Centralized control, limited cross-team collaboration Peer-led communities (collective governance) such as Security Guardians
Innovation Restricted, focus on following signed-off designs Encouraged, teams explore within a standards-based framework

Despite the benefits, many organizations struggle to let go of signoffs for a number of reasons, including:

  • Cultural resistance – In risk-averse cultures where failing fast is not accepted, leaders hesitate to let go of centralized control mechanisms.
  • Compliance concerns – In regulated industries, centralized approvals serve as control gates. The modern view replaces point-in-time trust with continuous compliance mechanisms—automated guardrails, real-time monitoring, and evidence collection—enabling even highly regulated environments to achieve compliance with small, autonomous teams operating within clear boundaries (“two-pizza team”).
  • Lack of infrastructure – Some organizations lack self-service platforms, automated compliance, or observability, so they fall back on signoff to manage risk.
  • Governance concerns – Traditional teams often view distributed decision-making as no governance rather than transformed governance.

The modern view offers significant benefits, though with governance considerations:

  • Speed and flexibility – Teams move faster without waiting for approvals, deploying AWS resources iteratively.
  • Empowerment and ownership – Builders using standards and ADRs feel accountable and actively shape architecture.
  • Innovation and experimentation – Self-service tools and AI guidance foster experimentation without delays.

Conclusion

You can empower your builders by rethinking your architecture signoff. In the modern view discussed in this post, architecture governance aligns with the pace and flexibility of the cloud, allowing teams to innovate within a shared framework. This approach values standards and autonomy over control, and transforms your architecture function into a strategic partner in a fast-evolving landscape.

To learn how to establish and maintain cloud-centered principles and patterns, refer to the platform architecture chapter of the AWS Cloud Adoption Framework and the AWS Culture of Security resources.

Related resources


About the author

Build and operate an effective architecture review board

Post Syndicated from Darrin Weber original https://aws.amazon.com/blogs/architecture/build-and-operate-an-effective-architecture-review-board/

The rapid change of pace in computing landscapes because of cloud, artificial intelligence, and technology innovation has challenged organizations to keep up while making sure that their initiatives and projects remain compliant with enterprise guidelines and policies. An effective architecture review board (ARB) can help an organization maintain compliance with enterprise guardrails while accelerating implementation of initiatives in their project pipeline.

In this post, we identify the components of an efficient architecture review process, define what an ARB is, and describe how to build and operate an effective enterprise ARB.

What is an architecture review board?

An ARB is a multi-disciplinary team responsible for reviewing solution architectures to help ensure compliance with enterprise guidelines, best practices, and supportability. Team members include stakeholders from different disciplines throughout your organization, which typically include Security, Development, Enterprise Architecture, Infrastructure, and Operations. Including a broad set of stakeholders reduces the amount of project recycle that happens when stakeholder representation is overlooked.

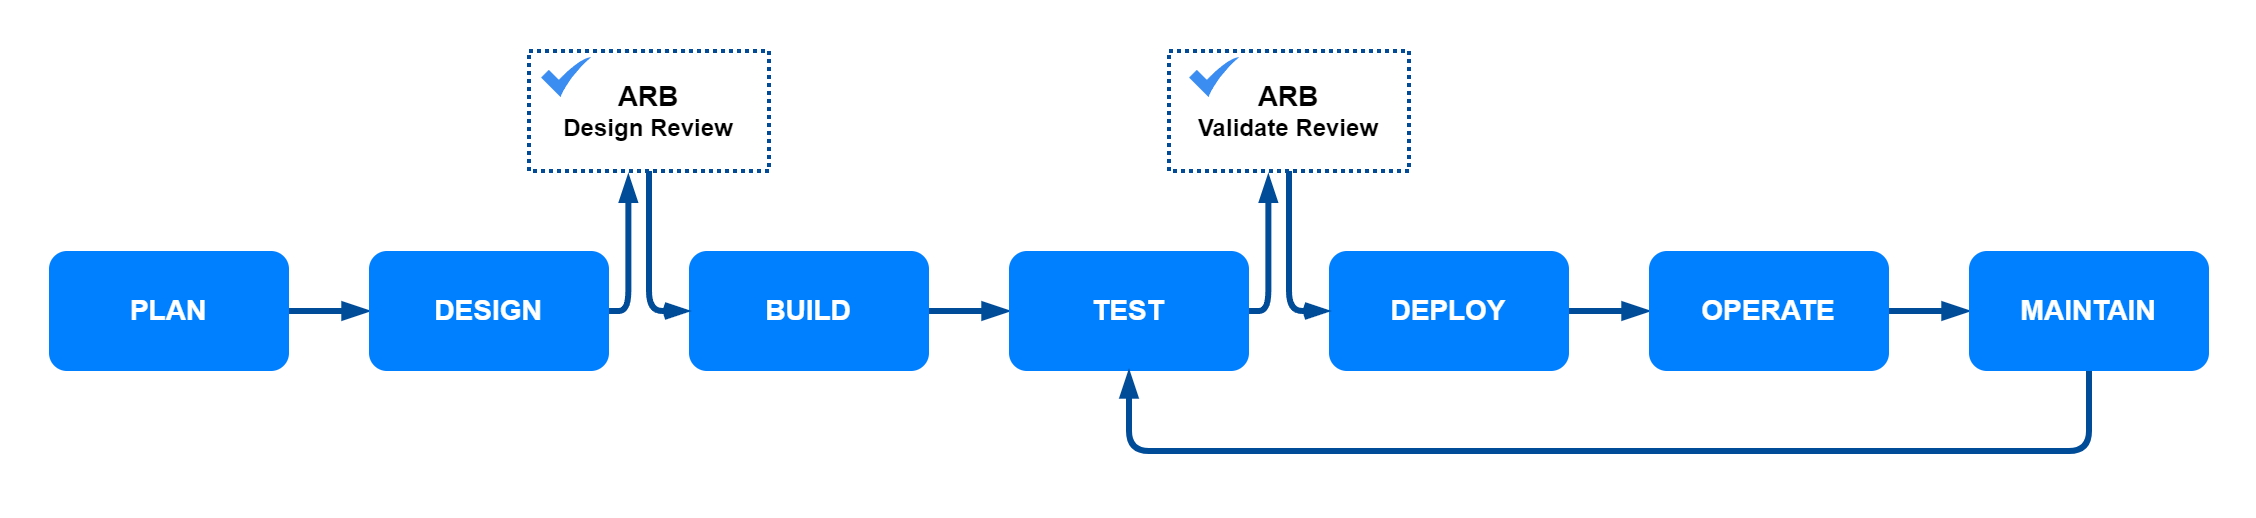
An ARB isn’t a standalone group, it operates within the context of your project implementation process, reviewing solution architectures, custom development, and purchased solutions to maintain enterprise compliance and alignment with goals. As shown in the following diagram, architecture review typically occurs after the design phase—before a build or purchase decision—and again before deployment to validate that the reviewed architecture matches the solution that was built.

Project implementation process with architecture review checkpoints

Most organizations recognize the benefits and value of establishing an ARB. However, they often struggle to define and operate one in a manner that maximizes the benefits, integrates with overall project execution processes, and satisfies the needs of all the stakeholders. An efficient architecture review process imparts organizational benefits such as reduced costs, minimized security events, and diminished technical debt.

Life without a formal architecture review process

One of the most pronounced issues with implementing and maintaining software architecture is the difficulty in achieving human consensus. In any organization, you’ll find a diverse range of team members—each with their own priorities, perspectives, and pain points. Without a formalized review process, these differences can lead to prolonged debates and stalled projects. We often find that many members tend to fall into one of these personas:

The Not Invented Here The Not Invented Here – This individual doesn’t trust any software unless it was built and operated by members of their company. They’re generally wary of any cloud solution and will expend development time to avoid capital expenditure.
The Wait a Minute The Wait a Minute – This individual has good feedback and their input is welcome, but they tend to wait until the last minute before providing any feedback, making it difficult to have productive conversations and act on any constructive criticism.
The Bottleneck The Bottleneck – This individual craves control and insists that all reviews, decisions, and conversations go through them. This makes scaling the architecture review process very challenging and decisions will often come down to the whim of this one person.
The Creative The Creative – This individual has passion for software and for creating things, but will often choose complexity over simplicity and turn their architectures into art projects.
The Perfectionist The Perfectionist – This individual tends to let the perfect be the enemy of the good. While their intentions are pure, this approach can result in delayed decision making and debates on topics that might not be worth the time of the board.
The Historian The Historian – This individual has been at the company for a long time and remembers every success and failure along the way. While the context this individual brings to the table is invaluable, teams must guard against only looking to the past as they try to shape the future.

Benefits of an architecture review board

Establishing an ARB within your organization can yield substantial benefits, enhancing both the quality and efficiency of your architecture. Some key advantages are:

Improved compliance

By systematically reviewing architectural decisions, the ARB helps ensure that designs adhere to company best practices, open standards, and regulatory requirements as set forth by your enterprise architecture.

Reduced technical debt

Technical debt—taking shortcuts in the development process that lead to future complications—is a common issue in software development. The ARB helps identify and mitigate technical debt early in the design phase. By enforcing architectural standards and promoting best practices, the board helps ensure that decisions are made with long-term sustainability in mind. This approach results in more robust, maintainable codebases and reduces the likelihood of future rework.

Efficiency with lowered costs

While a formal architecture review sounds like it might have the potential for increased red tape and lowered efficiency, the ARB instead contributes to operational efficiency by standardizing architectural practices across the organization. This uniformity allows for better resource allocation, faster deployment cycles, and more predictable project timelines. By catching potential issues early in the design phase, the ARB helps avoid costly rewrites and rework, which can lead to significant cost savings over time.

Supportability

Designing for supportability is crucial for the long-term success of any application. The ARB makes sure that architectures are built with maintainability in mind, making it easier for operations teams to manage and troubleshoot systems. This focus on supportability leads to fewer downtime incidents, faster resolution times, and overall higher system reliability. By making sure the composition of the ARB crosses all parts of the organization, supportability concerns can be surfaced earlier and help ensure that changes are properly socialized.

Security

Above all, security is the most critical output of an effective ARB. The ARB plays a pivotal role in embedding security into the architectural fabric from the outset. By conducting thorough security reviews and incorporating security best practices into every design, the ARB makes sure that applications are resilient against unintended disclosure, inadvertent access, and threat actors. This proactive approach not only protects sensitive data, but also builds trust with your customers and stakeholders.

Steps for effective architecture review boards

Whether looking to establish a new architecture review process or improve the effectiveness of a current ARB, we’ve identified eight key steps to make sure that an ARB operates in a way which realizes the benefits of a robust architecture review process while maintaining enterprise compliance. With the exception of leadership support, the steps aren’t presented in a particular order and can be implemented in parallel or in whatever order fits your organization and resource availability.

Leadership support

Identifying a sponsor on the executive leadership team is crucial to the success of the ARB. An executive sponsor fosters participation from stakeholders, representing key organizations such as Security, Development, and Operations, along with gaining their commitment to the review processes. The executive sponsor helps embed the ARB function within the enterprise’s project implementation process. Supported by the executive sponsor, the ARB’s reviews serve as a formal gate within the project process, reducing attempts to bypass the review processes.

Single source for guidance, policies, and best practices

Establish a single, well-known repository or index so that the entire enterprise has a single source of truth that establishes the basis for designing and reviewing architecture. A common repository doesn’t need to be complex. It can be a central document location, wiki, or file share that’s quickly discoverable. Commonly, an enterprise’s collection of guidelines and policies are dispersed and managed by each organization using different mechanisms and repositories. Best practices are often treated as folklore passed between team members. Project teams and ARB stakeholders need to share a common understanding of the enterprise’s collective intelligence consisting of guidelines, policies, and best practices.

As the project community’s collective understanding of the enterprise guidelines and policies grows, initial solution designs are better aligned, and reviews through the ARB accelerate. After a common repository is established, consider using generative AI to create a natural language chatbot, a design chatbot, to simplify access to the collective guidelines, policies, and best practices. See Amazon Bedrock or Amazon Q – Generative AI Assistant.

Defined stakeholders

Make sure that your disciplines have defined stakeholders on the ARB. A good starting point is to identify stakeholders from the Security, Enterprise Architecture, Development, Infrastructure, and Operations teams. Broad representation on the board minimizes recycles and delays later in the project, which can occur when stakeholders aren’t engaged in the review process from the beginning. A stakeholder’s responsibility is to focus on their area of subject matter expertise and commit a portion of their time to the ARB. Consider rotating stakeholders periodically to distribute knowledge and workload through the organization.

Gated process with documented decisions

As previously described, architecture reviews typically occur after design and before solution implementation or purchase. Optionally, another architecture review takes place before deployment to validate that the solution matches what was reviewed and approved. It’s important to complete the review before implementation or the purchase decision and to get stakeholder sign off. Otherwise, projects risk rework and delay later in the process, often impacting cost or schedule to a greater degree. Document each ARB action, including approvals, reasons for recycles, exceptions required, follow-ups needed, and so on. Documented decisions should be added to the project’s overall lifecycle documentation to benefit future inspection of project or similar solution architectures.

Establish an exception process

There will always be exceptions to your enterprise guidelines or policies. Plan for exceptions with a defined process for reviewing, escalating, and gaining approval. Include leadership from both IT and business areas in the assessment and sign-off on an exception. Most importantly, set expiration dates on the exceptions–they should not be granted indefinitely. Exceptions are typically granted to accommodate a temporary nonconformance to provide time to plan for and implement a better, long-term solution.

Architecture central repository

Establish a well known, central repository for solution architecture documents. Solution documentation should be treated as living artifacts that are maintained for the lifecycle of the use case. A central architecture repository benefits teams responsible for operating and maintaining solutions, along with design teams chartered with new solution design. After a repository is established, consider including your architecture documentation in the generative AI design chatbot mentioned previously.

Automate review process

Employ automated architecture review processes wherever possible. Automated review processes allow stakeholders to focus their time on their subject matter expertise instead of administrative tasks. Consider separate review processes based on an initiative’s complexity, cost, and impact. Schedule live meetings with the ARB for the most complex and impactful solutions, and use offline mechanisms, such as email, for other efforts. Define a universal architecture template to capture areas of interest for review and automate the Q&A and sign-off processes. Consider using generative AI to do initial automated design reviews against enterprise core best practices and policies to further streamline stakeholder review processes.

Architecture review process shepherd

Identify a shepherd to help ensure that solution architectures are reviewed and the ARB review processes are broadly understood. The shepherd functions as a liaison with executive sponsors for exceptions. While the shepherd can also be a stakeholder on the board, the shepherd is not the single overall decision maker. The shepherd champions the continuous improvement of the architecture review process and mechanisms.

Conclusion

In this post, we explored the benefits of establishing an architecture review board within an organization, emphasizing its role in maintaining compliance, reducing technical debt, and enhancing operational efficiency. We discussed the challenges organizations face in setting up an effective ARB and provided guidance on the essential components and steps required to build and operate a successful ARB. By following the outlined steps, organizations can maximize the benefits of an ARB, making sure that architectural decisions align with enterprise goals and standards while fostering a culture of continuous improvement and stakeholder collaboration.

For additional guidance on garnering the leadership support necessary for an effective ARB, see Well-Architected Framework: Provide executive sponsorship. For more details on the review process, see Well-Architected Framework: The review process and AWS Well-Architected Tool, an AWS Management Console-based service that provides a consistent process for measuring your architecture using AWS best practices. If you’re interested in establishing a natural language chatbot interface for your enterprise architecture information, see Amazon Bedrock, Amazon Q Business, or Build a contextual chatbot application using Amazon Bedrock Knowledge Bases.


About the authors

From virtual machine to Kubernetes to serverless: How dacadoo saved 78% on cloud costs and automated operations

Post Syndicated from Andreas Gehrig original https://aws.amazon.com/blogs/architecture/from-virtual-machine-to-kubernetes-to-serverless-how-dacadoo-saved-78-on-cloud-costs-and-automated-operations/

dacadoo is a global Swiss-based technology company that develops solutions for digital health engagement and health risk quantification. Their products include a software-as-a-service (SaaS)-based digital health engagement platform that uses behavioral science, AI, and gamification to help end users improve their health outcomes.

The company embarked on a journey to modernize an API to quantify health and lifestyle data plus a risk engine to calculate mortality and morbidity probabilities based on years of scientific research data.

To transform a virtual machine–based API service into a globally redundant, scalable health score and risk calculation solution dacadoo chose Amazon Web Services (AWS) technology. The service handles highly sensitive health data from a global customer base and must comply with regional regulations.

The result is a cost reduction of 78% and an infrastructure maintenance effort of less than an hour per year , allowing dacadoo to deliver and operate more AWS infrastructure without scaling its site reliability engineering (SRE) team, thanks to a high level of automation and an agile mindset.

In this post, we walk you step-by-step through dacadoo’s journey of embracing managed services, highlighting their architectural decisions as we go.

Background

The solution architecture went through a three-stage journey:

  1. Incubation – Single virtual machine on premises with disaster recovery (DR) in Switzerland
  2. Global and scalable – Multiple global Kubernetes clusters
  3. Operational excellence – Fully serverless and geo-redundant on AWS

Stage 1: Incubation with a virtual machine

After years of scientific research and development, the service was launched, running on a single on-premises virtual machine that used hypervisor technology to provide disaster recovery (DR). However, it had no high availability (HA) capability and it required manual recovery.

The application serving the API requests and the NoSQL database were both running on the same host. Software deployment and operating system maintenance were performed manually using Secure Shell (SSH)—a typical low-automation setup that also included downtime.

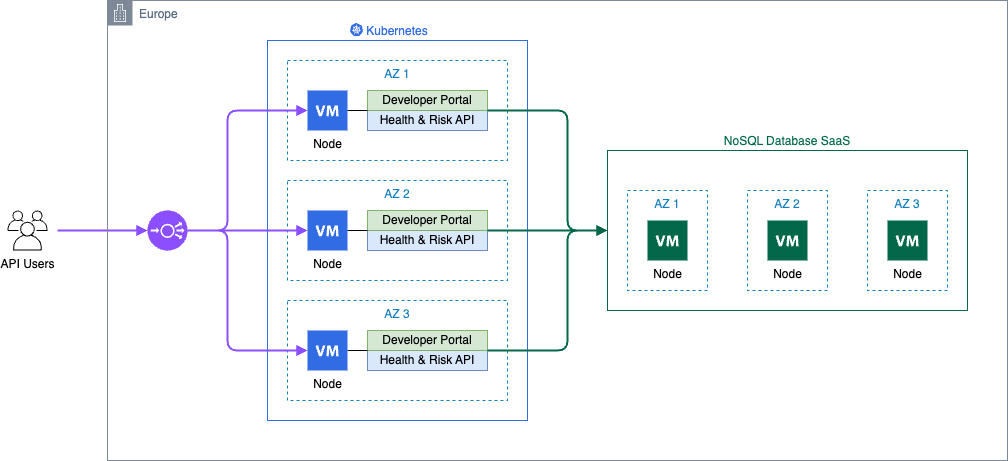
The following architecture diagram shows a virtual machine encompassing the monolithic application and its database.

Monolithic architecture

Challenges

A single virtual machine was quick to set up and inexpensive to operate, but it had considerable shortcomings. The health API was only available in Switzerland, infrastructure maintenance was performed manually, and software deployment was handled manually. Additionally, database backups were done using virtual machine snapshots, uptime monitoring only, and testing was conducted on the developer workstation.

Stage 2: Global and scalable with Kubernetes

At that time, dacadoo made a strategic decision to heavily invest in Kubernetes for managing containerized workloads on a global scale. As part of this technology rollout, the health score and risk service were migrated to Kubernetes.

Due to the geographically distributed customer base and low latency requirements, three Kubernetes clusters were deployed, one on each continent. The NoSQL database was hosted in proximity to the workload to reduce service latency and keep the migration effort low.

To reduce the operational maintenance, the NoSQL database was integrated as a SaaS offering, and monitoring was centralized using Datadog.

All cloud infrastructure was provisioned exclusively with Terraform, covering the Kubernetes cluster, NoSQL database , and integration with GitLab and Datadog.

dacadoo containerized the API service and used Gitlab continuous integration and continuous deployment (CI/CD) pipelines to deploy multiple environments and clusters on a global hyperscaler.

In retrospect, this was a typical replatform modernization project from virtual machine to Kubernetes, with a high level of automation and a SaaS-first approach.

The following diagram is the architecture for the container solution with managed NoSQL database.

Containers architecture

Challenges

The service faced several challenges, including increased costs from deploying three regional Kubernetes clusters across three environments, resulting in 27 cluster nodes and additional expenses from managing NoSQL database SaaS instances for each cluster. The complexity of CI/CD pipelines for multi-environment multi-cluster deployments added to the difficulty. Significant operational effort was required to keep infrastructure and Kubernetes components up to date.

Stage 3: Operational excellence with serverless

The Kubernetes-based architecture met the requirements, but some features in the dacadoo API service backlog needed to fit better with the application architecture at the time.

This was the right moment to take a holistic view of the infrastructure and software architecture and refactor the solution according to the latest AWS technologies and best practices, the next frontier for dacadoo’s engineering team.

Solution requirements

Requirements for the solution refactoring were as follows:

  • Keep the functionality of the API unmodified
  • Constrain data processing to a region of choice for compliance with local data protection laws
  • Avoid weekly patch cycles by exclusively using managed serverless services
  • Reduce costs by choosing services with a pay-as-you-go billing model
  • Delegate authentication to a dedicated service
  • Use an established web framework with an extensive ecosystem

Refactoring the apps

The API service has two components: a developer portal and the health score and risk calculations API. The database is only required for API keys, algorithm parameters, quotas, and usage statistics. Health data is processed regionally by the compute layer but not persisted, opening the door for a distributed database: Amazon DynamoDB global tables is the perfect fit for the solution. Writes are distributed to all connected Regions, whereas reads are local, providing low latency for complying with dacadoo service level agreements (SLAs).

The developer portal is a web UI with API documentation and API key management features. AWS Lambda is a great fit because it scales automatically and has a pay-per-request billing model.

The health and risk API uses algorithms implemented in the C programming language for short bursting, compute-intense simulations. These calls are wrapped by a REST API using the Python FastAPI framework. These characteristics make AWS Lambda a great fit.

Serverless architecture

HTTP requests are routed to the Lambda functions using Amazon API Gateway with AWS WAF for protection from malicious requests and attacks. Static assets are served from an Amazon Simple Storage Service (Amazon S3) bucket through API Gateway. The additional features of Amazon CloudFront aren’t required, and Amazon S3 reduces the complexity.

Amazon Route 53 provides a powerful feature known as latency-based routing, which allows it to direct DNS queries to the endpoint that offers the lowest latency for the requester.

This feature provides Regional high availability for API users without data processing location requirements. Alternatively, the user can call specific Regional endpoints to make sure requests are processed in the desired Region.

API authorization is HTTP header-based and is performed in the application with data stored in Amazon DynamoDB.

The following diagram is the architecture for a geo-redundant fully serverless solution.

Serverless architecture

With a dacadoo SRE team proficient in Python, they opted for Pulumi for its advanced features such as programming language flow control constructs, powerful configuration capabilities, and multi-cloud support.

For continuous integration, GitLab CI compiles the algorithm library, tests the FastAPI applications and packages everything. The application deployment is just an update of the AWS Lambda, a simple and reliable workflow.

Summary

The solution evolved from a managed infrastructure setup, where the customer held most of the responsibility, to an AWS managed service architecture.

Infrastructure provisioning evolved from manual, error-prone processes to powerful code-driven workflows in Pulumi. The SRE needed to enhance their software engineering skills to adopt Pulumi, transitioning from configuration-based approaches to designing and maintaining an infrastructure code base using object-oriented Python. This was part of dacadoo’s investment in the SRE team and broader modernization efforts. The serverless architecture enabled a GitOps engineering culture focused on productivity.

The transformation maximized scalability and availability while reducing costs and operational effort:

Virtual machine

  • Scalability: Low
  • Availability: Best effort
  • Infrastructure costs: Low
  • Maintenance effort: High

Kubernetes

  • Scalability: High
  • Availability: 99.95%
  • Infrastructure costs: High
  • Maintenance effort: Medium

Serverless

  • Scalability: Very high
  • Availability: 99.999% (with failover to another AWS Region)
  • Infrastructure costs: Low
  • Maintenance effort: Very low

The global redundancy elevates availability to an impressive 99.999% while keeping the costs low.

Conclusion

Migrating from a virtual machine to Kubernetes and ultimately to AWS Lambda demonstrates the progression of cloud engineering toward enhanced efficiency and scalability.

Each step in this journey reduced the complexity of managing resources while increasing flexibility and automation. Transitioning dacadoo’s API service to a fully serverless, geo-redundant architecture not only advanced the platform but also upskilled engineers, maintained a lean SRE team, and kept infrastructure costs low. Get started with your own AWS serverless solution.


About the Authors

Building a voice interface for generative AI assistants

Post Syndicated from Reynaldo Hidalgo original https://aws.amazon.com/blogs/messaging-and-targeting/building-voice-interface-for-genai-assistant/

Generative AI is revolutionizing how businesses interact with their customers through natural conversational interfaces. While organizations can implement AI assistants across various channels, phone calls remain a preferred method for many customers seeking support or information.

We’ll demonstrate how to create a voice interface for your existing Amazon Bedrock generative AI assistant, enabling customers to engage in phone-based conversations with your AI implementation.

Solution overview

Using Workflow Studio for Amazon Web Services (AWS) Step Functions, we built a voice communication interface that connects with the Amazon Nova Micro model in Amazon Bedrock (Figure 1). The demo application uses the base model to enable open-ended questions. Organizations can implement either Amazon Bedrock Agents or Flows to address specific business requirements.

A Step Functions workflow diagram illustrating a voice communication system integrated with Amazon Bedrock. The workflow shows a sequential process starting with call handling, followed by parallel branches: one for managing hold music and another for processing voice input through Amazon Transcribe and Amazon Nova Micro model. The diagram demonstrates the complete call flow from initial welcome message through question-answer cycles to call completion.

Figure 1 – Step Functions workflow that enables voice communication to a generative AI assistant

How it works:

  1. Inbound call arrives
  2. System plays welcome message
  3. System asks caller for questions
  4. Voice recording starts, stopping when silence is detected
  5. Parallel flows begin:
    • First flow
      1. Plays some music while the caller is on-hold
    • Second flow
      1. Transcribes the recording using Amazon Transcribe
      2. Sends transcribed question to the Amazon Nova Micro model in Amazon Bedrock
      3. Upon receiving the response, stops the on-hold music
  6. Text-to-speech plays the model’s answer
  7. System asks for additional questions and loops to Step 4 or ends the call

 Expanded capabilities and optimizations

These are potential improvements, additional functionalities, and advanced features that can enhance the demo application:

  • The transcription component is interchangeable with any speech-to-text generative AI model (including Whisper Large V3 Turbo on Amazon Bedrock Marketplace)
  • The PSTN audio service RecordAudio Action can be tuned to adjust silence duration and background noise levels
  • Enabling the PSTN audio service VoiceFocus feature to improve call clarity by reducing background noise and enhancing voice quality
  • PSTN audio service Session Initiation Protocol (SIP) media applications can also handle calls through SIP trunking by using Amazon Chime SDK Voice Connector, streamlining integration with existing phone systems
  • The UpdateSipMediaApplicationCall API is a PSTN audio service feature that lets you regain call control and apply new actions during active calls
  • Parallel workflow states allow user-friendly handling of API service calls by playing music during processing
  • PSTN audio service provides pay-per-minute rates with serverless, scalable telephony infrastructure

Deploying the solution

 The following steps allow you to deploy the voice communication interface workflow (Figure 1) together with the supporting serverless architecture for Step Functions and PSTN audio service integration. In a previous blog, we demonstrated how combining Step Functions and Amazon Chime SDK PSTN audio service streamlines the development of reliable telephony applications through a visual workflow design.

 Prerequisites:

  1. AWS Management Console access
  2. Node.js and npm installed
  3. AWS Command Line Interface (AWS CLI) installed and configured
  4. Enable access to the Amazon Nova Micro model through the Amazon Bedrock console

 Walkthrough:

The AWS Cloud Development Kit (AWS CDK) project on the AWS GitHub repository will deploy the following resources:

  • phoneNumberBedrock – Provisioned phone number for the demo application
  • sipMediaApp – SIP media application that routes calls to lambdaProcessPSTNAudioServiceCalls
  • sipRule – SIP rule that directs calls from phoneNumberBedrock to sipMediaApp
  • lambdaProcessPSTNAudioServiceCallsAWS Lambda function for call processing
  • roleLambdaProcessPSTNAudioServiceCalls – AWS Identity and Access Management (IAM) Role for lambdaProcessPSTNAudioServiceCalls
  • stepfunctionBedrockWorkflow – Step Functions workflow for the telephony application
  • roleStepfuntionBedrockWorkflow – IAM Role for stepfunctionBedrockWorkflow
  • s3BucketApp – Amazon Simple Storage Service (Amazon S3) bucket for storing customer questions recordings
  • s3BucketPolicy IAM Policy granting PSTN audio service access to s3BucketApp
  • lambdaAudioTranscription – Lambda function for audio transcription
  • lambdaLayerForTranscription – Lambda layer required for lambdaAudioTranscription
  • roleLambdaAudioTranscription – IAM Role for lambdaAudioTranscription

Follow these steps to deploy the CDK stack:

  1. Clone the repository.
git clone https://github.com/aws-samples/sample-chime-sdk-bedrock-voice-interface
cd sample-chime-sdk-bedrock-voice-interface
npm install
  1. Bootstrap the stack.
#default AWS CLI credentials are used, otherwise use the –-profile parameter
#provide the <account-id> and <region> to deploy this stack
cdk bootstrap aws://<account-id>/<region>
  1. Deploy the stack.
#default AWS CLI credentials are used, otherwise use the –-profile parameter
#phoneAreaCode: the United States area code used to provision the phone number
cdk deploy –-context phoneAreaCode=NPA
  1. Call the provisioned phone number to test the sample application.

Cleaning up:

To clean up this demo, execute:

cdk destroy

Conclusion

We demonstrated how organizations can add voice capabilities to their existing generative AI implementations using Amazon Bedrock. The solution enables customers to interact with AI assistants through traditional phone calls, expanding accessibility and user engagement. The demo application showcases an architecture combining AWS Step Functions and Amazon Chime SDK PSTN audio service, delivering natural voice conversations with AI models through quick deployment using visual workflows.

Organizations benefit from cost optimization with pay-per-minute pricing, enterprise-ready telephony integration through PSTN or SIP trunking, and automatic scaling to match customer demand. This foundation enables businesses to build practical AI applications ranging from all day customer service agents, to multi-language support services, and knowledge base assistants. By following this solution, you can quickly extend your generative AI investments to voice channels, providing more value to your customers while maintaining operational efficiency.

Contact an AWS Representative to know how we can help accelerate your business.

Master architecture decision records (ADRs): Best practices for effective decision-making

Post Syndicated from Christoph Kappey original https://aws.amazon.com/blogs/architecture/master-architecture-decision-records-adrs-best-practices-for-effective-decision-making/

Architecture decision records (ADRs) help you document and communicate important process and architecture decisions in your engineering projects. Based on our experience implementing over 200 ADRs across multiple projects, we’ve developed best practices that can help you streamline your decision-making processes and improve team collaboration.

In this post, you’ll learn:

  • How to implement ADRs in your organization
  • Best practices based on more than 200 ADRs across multiple projects
  • Practical tips for streamlining architectural decision-making
  • Real-world examples from projects with 10 to more than 100 team members

Common challenges in architecture decision-making

Before implementing ADRs, your teams might face these common challenges:

  1. Team alignment – Development teams spend a huge part of their time (20 –30%, based on our project experience of the past 3 years) coordinating with other teams, which can slow down feature deployment and increase costs through repeated architecture refactoring
  2. Design flexibility – Finding the right balance between upfront design and evolving architecture when working with agile and DevOps approaches
  3. Nonfunctional requirements – Making trade-offs between security, maintainability, and scalability requirements
  4. Changing requirements – Adapting architectural decisions to evolving business goals while maintaining system integrity
  5. Knowledge transfer – Onboard new team members efficiently and make sure they follow the team’s current way of working

How to streamline the decision-making process

We base the recommendations in this post on our experience with several projects, working with teams with fewer than 10 team members as well as complex projects with 100 team members across 10 work streams. We embarked on ambitious projects with a green-field start as well as projects covering ongoing development of new features in production. Especially in teams with 100 people contributing to the code base, we faced the challenge of making sure that collaboration was seamless and decision-making consistent.

To address this challenge, we implemented an ADR mechanism, which served as our guiding light throughout the project’s lifecycle. After more than 3 years of following this approach, we’ve amassed a wealth of experience and best practices that we’re excited to share with the software development community. By capturing the context, alternatives considered, and the rationale behind each decision, ADRs foster transparency, knowledge-sharing, and accountability within teams. Our goal is to guide you through the process of writing effective ADRs with the following best practice recommendations:

  1. Keep ADR meetings short and focused – Effective ADR meetings should be concise and time-bound. Aim to keep them 30–45 minutes maximum. This focused approach keeps discussions on track and participants engaged throughout the process.
  2. Embrace the readout meeting style – Adopt the readout meeting style, where participants spend 10–15 minutes reading the ADR document. Encourage attendees to provide written comments on sections, paragraphs, or sentences that require clarification or where they have differing opinions. This approach promotes active engagement and fosters a bias for action and frugality.
  3. Maintain a cross-functional yet lean participant list – Invite representatives from each team that might be affected by the architectural decision but strive to keep the total number of participants below 10. This cross-functional representation provides diverse perspectives while maintaining a lean and efficient decision-making process, aligning with the principles of frugality and bias for action.
  4. Focus on a single decision – Keep ADRs concise by focusing on a single decision. Don’t hesitate to split up decisions if necessary. Concentrating on one decision at a time simplifies the decision-making process so that participants can thoroughly evaluate the impact during readout sessions. This approach aligns with the principles of ownership and customer obsession.
  5. Separate design from decision – Use a separate design document mechanism to explore alternative options thoroughly. Reference these design documents within the ADR, adhering to the principles of invention and simplification.
  6. Address comments and resolve feedback – Actively follow up on comments received during the ADR review process. Resolve all comments, either by incorporating changes or by discussing and reaching a consensus with the comment author. This practice demonstrates a commitment to delivering results and fostering a sense of ownership.
  7. Push for a timely decision – Avoid prolonged discussions and multiple readout meetings. Based on our experience, one to three ADR readouts should be sufficient. If more sessions are required, reevaluate the dependencies and consider reducing the number of invitees or reducing the scope of the ADR. Most of the decisions are two-way door decisions, meaning that they can be changed with little impact in the future. It’s always better to make a decision and try it fast instead of endlessly discussing it. This approach aligns with the AWS principles of working backwards, customer obsession, delivering results, and being right a lot.
  8. Embrace team collaboration – Approving an ADR is a team effort. The author must own the document and gather feedback from all affected teams before finalizing the decision. This practice encourages having backbone, disagreeing and committing, and fostering a collaborative environment.
  9. Maintain and follow the process – Keep ADRs up to date and follow the established process. If an ADR supersedes a previous one, document the change and link the new ADR in the superseded document. Insist on the highest standards by adhering to the defined processes—consider ADRs as a team law.
  10. Centralize ADR storage – Store ADRs in a central location accessible to all project members, regardless of their team affiliation. This practice promotes transparency and makes sure that architectural decisions are readily available to everyone involved.

Implementation tips and success measures

When implementing these practices, we recommend that you start small with a pilot team, create clear templates, and establish review cycles. Defining success measures such as the time to decision, team satisfaction, architecture rework reduction, or cross-team collaboration improvement help to evaluate your decision-making process

Conclusion

By implementing these best practices for ADRs, you’ll streamline your decision-making processes, foster collaboration, and make sure that architectural decisions are well-documented, communicated, and aligned with your organization’s principles and goals. Embrace these practices and witness the positive impact they have on the success of your software projects.

Read the AWS Prescriptive Guidance for an introduction into ADRs and an example ADR or the homepage of ADR GitHub organization.


About the Authors

Pilot light with reserved capacity: How to optimize DR cost using On-Demand Capacity Reservations

Post Syndicated from Antoine Boucherie original https://aws.amazon.com/blogs/architecture/pilot-light-with-reserved-capacity-how-to-optimize-dr-cost-using-on-demand-capacity-reservations/

For digital enterprises to remain competitive, resilience is essential for maintaining reliability and building customer trust. End users expect applications to be available 24 hours a day, leading companies to develop increasingly sophisticated methods to provide continuous operation of critical services. Some companies, such as financial services companies, have to meet regulatory requirements such as Digital Operational Resilience Act (DORA) and are expected to manage the risk of outsourcing critical applications. They must design for high availability and plan for potential impairments. By proactively planning for potential disruptions, they’re not just mitigating risks – they’re building trust and delivering unparalleled value to their customers.

When assessing your own applications, you should define a set of objectives, perform a business impact analysis and a risk assessment. This way, you can estimate the impact to the business if the application isn’t available. This results in categorization of the applications and influence their design according to the AWS resilience lifecycle framework. Each application is given a specific Recovery Point Objective (RPO) and Recovery Time Objective (RTO), depending on its criticality for the business.

Not all applications fall in the most critical category. You allocate resources according to the results of the assessment and make trade-offs when designing applications. For example, you’ll have a more stringent RTO and RPO for—and be willing to spend more time and money on—a critical application than on a less critical application. The challenge becomes how to minimize the risk of breaching a specific RTO while optimizing for resources, such as cost and operational complexity.

At AWS, we provide guidance through the Well-Architected Framework and specifically within the Reliability pillar. Disruption can happen at several levels, and we recommend that you explore and prepare for four types of disruptions in the AWS Resilience Hub: application, infrastructure, Availability Zone, and AWS Region.

We recommend that you use managed services and make sure that all production workloads are designed to take advantage of multiple Availability Zones in AWS Regions. If your application also needs to be protected against the unlikely risk of Regional impairment, you should consider a multi-Region disaster recovery (DR) strategy.

You can select from several DR strategies: backup and restore, pilot light, warm standby, and multi-site active-active:

  • Backup and restore – This strategy might not provide the necessary RPO or RTO required for a highly critical application.
  • Multi-site active-active – This strategy increases significantly the cost and operational complexity of your application.
  • Pilot light – This strategy allows for a RPO or RTO in the tens of minutes by having the data asynchronously copied to the secondary Region and ready to be accessed. However, unlike a warm standby, the application servers aren’t deployed and aren’t ready to serve traffic. The pilot light strategy allows for a lower cost but brings a risk that you might not be able to provision the compute capacity you need when you want to fail over to the secondary Region, especially if you require a specific instance type.

In this post, we explore an intermediate strategy between the pilot light and the warm standby strategies: pilot light with reserved capacity. You can use this strategy to reserve compute capacity in a secondary Region while also limiting cost.

The following diagram illustrates where the pilot light with reserved capacity solution lies in the spectrum of disaster recovery strategies.

spectrum of disaster recovery strategies

Reserving capacity, on demand

On-Demand Capacity Reservations were launched in 2018. They make it possible to reserve capacity in the Availability Zone of your choice without a long-term contract. You have the flexibility to create, modify, or cancel reservations at your discretion. It’s especially well-suited if your application is dependent on a specific instance type or size.

Optimizing the cost of On-Demand Capacity Reservations with a Savings Plan

On-Demand Capacity Reservations is a reservation mechanism and doesn’t require a commitment. However, you can optimize your spending by combining the capacity reservation with an AWS Savings Plan. By using Savings Plans, you can achieve up to a 72% discount, a very significant cost reduction for DR instances that have to stay available all year long.

Optimizing the cost of On-Demand Capacity Reservations by sharing Capacity Reservations

To further optimize the cost, you can use your reserved capacity in another account when you don’t need it for DR.

Here’s an example in which we share On-Demand Capacity Reservations with our development and test account:

We have a three-tier application running in production in a primary AWS Region. This application is composed of a load balancer forwarding traffic to a fleet of application servers running on Amazon Elastic Compute Cloud (Amazon EC2) instances, backed by an Amazon Relational Database Service (Amazon RDS) database. All services used by this application are configured to use multiple Availability Zones in this primary Region.

We use the pilot light strategy, so the application data is being replicated to the disaster recovery environment in a secondary Region using Amazon RDS cross-Region read replicas. However, the load balancer and EC2 services aren’t running in DR to limit cost and operational complexity. Following best practices, each environment is running in a different AWS account.

The following diagram illustrates the pilot light strategy setup for our example.

pilot light strategy setup for our example

To reserve capacity in case of failover to the secondary Region, we create an On-Demand Capacity Reservation in the DR account, according to our baseline compute capacity. Because we don’t need this capacity until we fail over the application from the primary to the secondary Region, we share those On-Demand Capacity Reservations with a development and test account hosting our nonproduction environment in the secondary Region. On-Demand Capacity Reservations are Availability Zone specific (and hence Region specific) and can be shared with either AWS accounts or AWS Organizations using AWS Resource Access Manager (AWS RAM).

Best practices are to share those On-Demand Capacity Reservations with a nonproduction organizational unit (OU) within an organization or to directly share with the account(s) hosting the testing environments (for example, user acceptance testing or preproduction). Those environments are usually very similar to the production account in baseline sizing, in order to perform load and performance testing. This is an important point: you want to be able to retrieve those On-Demand Capacity Reservations when needed without impacting other critical applications.

The following diagram illustrates the Capacity Reservations sharing with the development and test account.

Capacity Reservation sharing with development and test account

If an impairment affects our production environment in the primary Region, we can trigger failover to the secondary Region. To reclaim capacity, we need to terminate the EC2 instances running in our development and test account. Capacity becomes available nearly immediately after these instances are successfully terminated. Separately, we can also stop the sharing of On-Demand Capacity Reservations to make sure that the development and test account can’t consume that capacity again. Know that merely unsharing your reservation without terminating development and test instances might not result in complete or immediate capacity retrieval. This is because when you unshare an On-Demand Capacity Reservation, the instances in the consumer account continue to run, and capacity is only returned to the owner account if additional capacity is available in the Amazon EC2 service on-demand pool.

The following diagram illustrates the failover to the DR environment in a secondary Region.

cancellation of the capacity reservations sharing

Steps

Here is a possible approach to take advantage of On-Demand Capacity Reservations to reduce the application’s total infrastructure cost:

  1. Calculate the baseline compute capacity necessary for the DR environment in the secondary Region in the event of failover, including the compute that might already be running in this secondary Region for data stores (for example, a Kafka broker running on Amazon EC2). How much vCPU and RAM is required or what are the exact EC2 instances necessary to host the whole application in case of failover of the production from the primary to the secondary Region.
  2. Create an On-Demand Capacity Reservation for the exact EC2 instances that the application need as a baseline in the DR account. Capacity Reservation Fleet is also a possible choice to reserve capacity across multiple instance types, which is often the case for Amazon Elastic Kubernetes Service (Amazon EKS) or Amazon Elastic Container Service (Amazon ECS) clusters, for example. Creating a Capacity Reservation Fleet will create multiple Capacity Reservations that can be shared independently. It’s also recommended to apply for Savings Plans on those On-Demand Capacity Reservations to save up to 72%.
  3. Share those On-Demand Capacity Reservations from the DR account to one or several accounts, depending on your need. In our example, we share the On-Demand Capacity Reservations with the development and test account, effectively allowing the development and test environment to use compute capacity that has already been reserved.
  4. In case of impairment in the primary Region, terminate the development and test instances first and then stop the On-Demand Capacity Reservation sharing The DR account will recover those reservations. If you want to keep the development and test instances, you will be charged at the on-demand rate.
  5. Redeploy in an automated manner the application in the DR account on new EC2 instances behind a load balancer.

Benefits

By purchasing On-Demand Capacity Reservations in the DR account, you make sure that you always have Amazon EC2 capacity access when required and for as long as you need it. By sharing those On-Demand Capacity Reservations with another AWS account or organization, you can share the cost of the application’s compute capacity with other environments, reducing your application’s total cost of ownership. The additional cost of the DR instances can even reach zero, if your instances are completely consumed by nonproduction environments such as development and testing.

DR savings over On-Demand
Compute Savings Plan – 1 year, no upfront Around 27% (for example, for m7i instance)
Compute Savings Plan – 3 years, all upfront Up to 66%
Instance Savings Plan – 3 years, all upfront Up to 72%
Reservation shared and consumed 100% by development and test environment Up to 100%

Limits

Although you can reserve DR capacity at a minimal cost using the pilot light with reserved capacity solution, there are some limits to keep in mind.

Firstly, we advise looking at this solution only if the Recovery Time Objective of the application, in case of Regional disruption, is in hours because you need to take into account the time needed to:

  • Detect the impairment in the primary Region.
  • Trigger the failover procedure.
  • Terminate the used instances to retrieve capacity (estimated time in minutes)
  • Stop the On-Demand Capacity Reservations sharing and automatically retrieve them in the DR account (estimated time in minutes).
  • Launch the compute infrastructure with the necessary application software in the DR account. You need to make sure that it matches the On-Demand Capacity Reservations according to the criteria used (open or targeted)

If your application requires a lower RTO, we recommend exploring the warm standby strategy.

Secondly, this strategy can only be used for application servers running EC2 instances and ECS or EKS clusters on EC2 because On-Demand Capacity Reservations aren’t available for managed services such as AWS Fargate or AWS Lambda. For those managed services, we recommend having them up and running like in a warm standby strategy, with a minimum baseline capacity that you’re comfortable with.

Thirdly, it requires some nonproduction development and test usage in the selected secondary Region to use the shared On-Demand Capacity Reservation.

Finally, it’s important to consider that this solution brings some complexity and extra operational work. You should plan well ahead, automate the operational tasks where possible, but most importantly, regularly test that the failover of the application works according to plan. We encourage you to perform your own game days to support your operational resilience.

Deciding whether this strategy is a good fit for your application will ultimately be a decision based on your business and regulatory requirements.

Conclusion

In this post, we explained how to reserve capacity in a secondary Region using On-Demand Capacity Reservations. We highlighted how cost can be optimized using Savings Plans and by sharing reserved capacity with noncritical workloads. We saw how we can recover that capacity for the DR environment, in the event of a disaster, to allow the application to continue to serve end users. We looked at the benefits and limits of the pilot light with reserved capacity solution and the necessary steps to put it in place.


About the Authors

Visually build telephony applications with AWS Step Functions

Post Syndicated from Reynaldo Hidalgo original https://aws.amazon.com/blogs/messaging-and-targeting/visually-build-telephony-applications-with-aws-step-functions/

Developers face numerous challenges when building telephony applications: managing unpredictable user responses, handling disconnections, processing incorrect inputs, and addressing errors. These challenges extend development cycles and create unstable applications that fail to meet user expectations.

This blog demonstrates how Amazon Web Services (AWS) Step Functions, combined with Amazon Chime SDK Public Switched Telephone Network (PSTN) audio service, offers a solution to overcome these challenges.

Overview of the solution

To demonstrate our solution, we built a sample telephony application that lets business owners manage customer calls through a dedicated business phone number. This solution helps small business owners separate personal and business communications, while managing all calls from their existing phone.

The beta version of this sample application delivers these six core call flows:

  1. During business hours: Routes incoming customer calls to the business owner
  2. After hours: Enables customers to leave voice messages
  3. Message retrieval: Allows owner to access customer voice messages
  4. Business caller ID: Enables owner to call customers using the business number
  5. Call scheduling: Permits owner to schedule customer calls for later in the day
  6. Automated calling: Initiates scheduled calls between owner and customer automatically

Using Workflow Studio, we built a Step Functions workflow (Figure 1) that processes all six call flows and handles unexpected scenarios.

Figure 1 – Visual diagram of a telephony workflow created in Workflow Studio for Step Functions, showing six interconnected call routing paths with decision points and error handling states. Each path represents a different customer interaction scenario, connected by arrows indicating the flow direction.

Figure 1 – Step Functions telephony workflow designed in Workflow Studio

How it works

AWS Step Functions enable agile visual workflow design, through pre-built components and error handling rules. This creates workflows composed of event-driven states that input, process, and output JavaScript Object Notation (JSON)-formatted messages. The PSTN audio service streamlines telephony applications through its serverless approach using a request/response programming model. It invokes AWS Lambda functions with Events and waits for Actions responses, both in predefined JSON formats. This shared JSON format enables seamless integration between the PSTN audio service and Step Functions, leading us to design a serverless architecture (Figure 2) that allows for bidirectional JSON message exchange between the two services.

Figure 2 – Architectural diagram showing the integration flow between AWS Step Functions and PSTN audio service. Arrows indicate JSON message exchange between services, with Lambda functions handling the communication. The diagram illustrates the serverless architecture components and their connections in a top-to-bottom layout.

Figure 2 – Serverless architecture for Step Functions and PSTN audio service integration

Main components:

  • eventRouter: Lambda function managing JSON message exchange
  • appWorkflow: Step Functions implementing call flow logic
  • actionsQueue: Amazon Simple Queue Service (Amazon SQS) queue storing response actions

Architecture flow:

  1. PSTN audio service receives inbound call
  2. Service sends NEW_INBOUND_CALL event to eventRouter
  3. eventRouter creates the actionsQueue
  4. eventRouter asynchronously executes appWorkflow with event data
  5. eventRouter begins long-polling from actionsQueue, waiting for next action(s) message
  6. appWorkflow processes JSON-formatted event data, computing next action(s)
  7. appWorkflow queues next action(s) using Amazon SQS SendMessage API with Wait for Callback with Task Token integration pattern to stop the workflow until the next event call is received
  8. eventRouter retrieves and removes action(s) from actionsQueue
  9. eventRouter returns action(s) to PSTN audio service

Observations:

  • eventRouter code logic is generic and agnostic from the calls and different Step Function workflows
  • eventRouter queries an environment variable to determine the workflow to call
  • Pairs of actionsQueue and appWorkflow instances lives for the duration of each call
  • eventRouter is responsible for the creation and deletion of each actionsQueue
  • appWorkflow instances are created by the eventRouter at the start of each call
  • appWorkflow instances complete its execution when all parties involved on the call hang up

Building your telephony application

Prerequisites:

Implementation Guidelines:

  • Create dedicated Step Functions workflows for each telephony application
  • Design and implement workflows using Workflow Studio
  • Use a Standard workflow type to accommodate extended call durations
  • Update the eventRouter Lambda function’s “CallFlowsDIDMap” environment variable to map phone numbers to their workflow Amazon Resource Name (ARN)
  • Set workflow variables in the “Init” state Variables tab (Figure 3). The eventRouter function automatically sets “QueueUrl”, and adding other variables here removes the need for external storage
Figure 3 – Screenshot of Workflow Studio's Variables tab showing an editable text box for JSON data entry. The interface displays a code editor with syntax highlighting for entering variable names and their values that persist throughout the workflow execution.

Figure 3 – Step Functions “Init” state Variables tab showing workflow data configuration

  • Configure Choice state rules to route calls based on conditions. Rules one through three (Figure 4) handle call routing based on inbound/outbound direction, owner/customer identification, while the default rule manages unexpected scenarios.
Figure 4 – Screenshot of Workflow Studio's Choice state configuration panel. The interface shows a rules editor where multiple condition blocks are displayed. Each block contains dropdown menus and input fields for setting call routing logic based on variable values. The rules appear in a vertical list with options to add, edit, or remove conditions.

Figure 4 – Step Functions Choice state defines rules for call routing decisions

  • Configure the SQS: SendMessage state (Figure 5) to instruct the next action to the PSTN audio service by:
    • Formatting the message content to match supported actions for the PSTN audio service
    • Setting TransactionAttributes to pass back and forth the values of the “WaitToken” and “QueueUrl” throughout the call duration
    • Enabling the Wait for Callback with a Task Token integration pattern
Figure 5 – Screenshot of the SQS: SendMessage state configuration in Step Functions Workflow Studio. The interface shows three main concepts: a message content formatter for PSTN audio service actions, transaction attribute fields for the WaitToken and QueueUrl values, and callback integration pattern settings. The message content input section displays input fields and options for setting up the message structure that enables communication between Step Functions and the PSTN audio service.

Figure 5 – SQS: SendMessage state configuration for PSTN audio service callback integration

  • Leverage AWS service integration states to interact with other AWS services directly from the workflow.
    • Example: Use a DynamoDB PutItem state (Figure 6) to store Amazon Simple Storage Service (Amazon S3) recording files, including bucket name and key, in Amazon DynamoDB.
Figure 6 – Screenshot of Step Functions Workflow Studio showing a DynamoDB PutItem state configuration. The interface displays fields for setting up direct interaction with DynamoDB to store S3 recording file information. The configuration panel includes input parameters for the DynamoDB table, item details, and S3 bucket and key values.

Figure 6 – AWS service integration states enable direct service connections without custom code

  • Utilize JSONata expressions (Figure 7) to minimize the number of Lambda functions.
    • Example: For Amazon EventBridge scheduling, compute time expressions using JSONata functions [$fromMillis(), $millis(), number()] and string concatenation to handle customer call scheduling.
Figure 7 – Screenshot of Step Functions Workflow Studio showing JSONata expression configuration. The interface displays a code editor with syntax highlighting where time calculation expressions are written using JSONata functions like $fromMillis(), $millis(), and number(). The panel demonstrates how to transform data directly within the workflow, eliminating the need for separate Lambda functions. Example expressions show date and time calculations for EventBridge scheduling.

Figure 7 – JSONata expressions for direct data transformation without Lambda functions

  • Use Step Functions error handling with success and fail states (Figure 8) to manage error paths and call termination results.
Figure 8 – Screenshot of Step Functions Workflow Studio showing the error handling configuration interface. The panel displays multiple state configurations: error catching paths for failed calls, success state definitions for completed calls, and termination handling settings. The interface includes dropdown menus and input fields for defining error types, retry attempts, and fallback actions. Visual connections between states illustrate the error handling flow from detection through resolution.

Figure 8 – Call error handling and termination setup

Key benefits

This approach for building telephony applications offers multiple advantages:

  1. Visual workflow-based designer
  2. Self-document call flow logic
  3. Managed versioning and publishing
  4. Native integration with AWS Services
  5. Visual log and inspection for each call
  6. Auto-scalable
  7. Pay-per-use pricing

Deploying the solution

 The following steps allows you to deploy the sample telephony application together with the serverless architecture (Figure 2).

 Prerequisites:

  1. AWS Management Console access
  2. Node.js and npm installed
  3. AWS Command Line Interface (AWS CLI) installed and configured

 Walkthrough:

The Cloud Development Kit (CDK) project on the AWS GitHub repository will deploy the following resources:

  • phoneNumberBusiness – Provisioned phone number for the sample application
  • sipMediaApp – SIP media application that routes calls to lambdaProcessPSTNAudioServiceCalls
  • sipRule – SIP rule that directs calls from phoneNumberBusiness to sipMediaApp.
  • stepfunctionBusinessProxyWorkflow – Step Functions workflow for the sample application
  • roleStepfuntionBusinessProxyWorkflowIAM Role for stepfunctionBusinessProxyWorkflow
  • lambdaProcessPSTNAudioServiceCalls – Lambda function for call processing
  • roleLambdaProcessPSTNAudioServiceCalls – IAM Role for lambdaProcessPSTNAudioServiceCalls
  • dynamoDBTableBusinessVoicemails – DynamoDB table to store customer voicemails
  • s3BucketApp –S3 bucket for storing system recordings and customer voicemails
  • s3BucketPolicy IAM Policy granting PSTN audio service access to s3BucketApp
  • lambdaOutboundCall – Lambda function for placing scheduled customer calls
  • roleLambdaOutboundCall – IAM Role for lambdaOutboundCall
  • roleEventBridgeLambdaCall – IAM Role to allow the EventBridge service to execute lambdaOutboundCall

Follow these steps to deploy the CDK stack:

  1. Clone the repository
git clone https://github.com/aws-samples/amazon-chime-sdk-visual-media-applications 

cd amazon-chime-sdk-visual-media-applications 

npm install
  1. Bootstrap the stack
#default AWS CLI credentials are used, otherwise use the –-profile parameter
#provide the <account-id> and <region> to deploy this stack 
cdk bootstrap aws://<account-id>/<region>
  1. Deploy the stack
#default AWS CLI credentials are used, otherwise use the –-profile parameter
#personalNumber: the personal phone number of the business owner in E.164 format 
#businessAreaCode: the United States area code used to provision the business number 
cdk deploy –-context personalNumber=+1NPAXXXXXXX –-context businessAreaCode=NPA

Call the provisioned phone number to test the sample application. Optionally, edit the workflow to update the business name and working hours on the “Init” Task state, in the Variables tab.

Cleaning up:

To clean up this demo, execute:

cdk destroy

Conclusion

This blog demonstrates how combining AWS Step Functions and Amazon Chime SDK PSTN audio service streamlines the development of reliable telephony applications through visual workflow design and managed error handling. We provided a sample application, implementing six core business phone features, showcasing how the solution effectively manages multiple conditional paths and edge cases like disconnections and invalid inputs.

The serverless architecture created enables seamless integration between the two services through JSON-based communication, while providing automatic scaling and pay-per-use pricing. Together, these components create a robust foundation for building sophisticated telephony applications that reduce maintenance costs and enhance reliability.

Contact an AWS Representative to know how we can help accelerate your business.

Build an enterprise API management solution using Amazon API Gateway

Post Syndicated from Roger Zhang original https://aws.amazon.com/blogs/architecture/build-an-enterprise-api-management-solution-using-amazon-api-gateway/

Enterprises face many challenges when they build and manage application programming interfaces (APIs). These challenges include security controls, version management, traffic control, and usage analytics. As digital businesses expand, a mature API management (APIM) solution is crucial for ensuring scalability, security, and operational efficiency.

This blog post shows how you can use Amazon API Gateway—along with AWS Lambda, Amazon DynamoDB, and other AWS services—to create a comprehensive and customizable APIM solution. This solution addresses the complex requirements of large enterprises managing APIs at scale.

Core features of APIM

API Management (APIM) centralizes the management and publishing of APIs for the entire enterprise, acting as a hub between clients, applications, and administrators on one side, and internal services, external systems, and large language models (LLMs) on the other, as shown in the following figure.

APIM capabilities

The key features of APIM include:

  • Security and governance
    • Authentication, authorization, rate limiting, and security policy enforcement.
    • Helps ensure APIs meet organizational or industry standards.
  • Monitoring and logging
    • Provides monitoring, alarms, and logging to track API performance and troubleshoot issues quickly.
  • Customization and transformation
    • Offers protocol and field transformations, plus orchestration and aggregation.
    • Makes it easier to integrate with different systems and meet various client needs.
  • API lifecycle management
    • Publishing, rollback, version control, and documentation.
    • Streamlines development and maintenance throughout the API lifecycle.
  • Developer and business tools
    • Portals for developers, business owners, and administrators to manage documentation, billing, and analytics.
  • Integration with LLMs
    • Specialized adapters, proxy configurations, and switching to integrate AI models seamlessly.
  • Flexible deployment options
    • Canary releases, pipeline automation, and other advanced release strategies.
    • Helps ensure stable, controlled API updates.

Unified management of multiple API gateways

API Gateway enforces resource limits of 300 resources per gateway, with a hard limit of 600. For enterprises that require more resources, managing multiple gateways individually can be time-consuming and error prone. APIM simplifies this by integrating API Gateway, Lambda, and DynamoDB; creating a centralized platform for managing APIs across multiple gateways. This integration streamlines the process, making it easier to scale and maintain APIs.

API lifecycle management

Managing API versions, publishing updates, and maintaining documentation often requires separate tools and manual processes, leading to inefficiencies. APIM centralizes these tasks in one portal, offering version control, publishing workflows, and rollback options. This streamlines the API lifecycle, ensuring consistency and reducing the chances for errors.

Enhanced security

Enterprises often need to implement different authentication strategies for various clients. These configurations typically require custom Lambda logic and database lookups, adding complexity and cost. APIM introduces configurable security policies that allow client-specific authentication without the need for additional custom code, reducing both complexity and operational overhead.

Customization and transformation

Enterprises frequently handle diverse client requests that involve different formats and protocols. Traditional API management approaches might struggle to support such variations. APIM allows for seamless protocol and field transformations, enabling integrations that meet a wide range of client requirements without additional development effort.

Developer portal

Developers need clear documentation, easy testing environments, and efficient API key management to work effectively. Traditional systems often lack these features, slowing down adoption. APIM provides a developer portal that consolidates API documentation, offers sandbox environments for testing, and simplifies API key management, reducing onboarding time and improving the developer experience.

Logging and monitoring

Log management is key to maintaining API performance, diagnosing issues, and gaining insights into usage. APIM uses API Gateway custom access logging, allowing teams to define logs based on business needs; whether creating separate CloudWatch metrics for each API path or exporting data to external platforms like ELK or Grafana.

Architecture overview

The APIM architecture, shown in the following figure, includes a management state (represented by numbers) and a runtime state (represented by letters). Both parts use a serverless paradigm.

APIM Architecture

Management state

The management state includes the following elements:

  1. Administrator portal access: Administrators access the APIM solution through a secured web portal.
  2. API Requests to APIM Lambda: Requests from the administrator’s API go through API Gateway, which then invokes the APIM Lambda function. This function handles logic related to configuration changes and other administrative actions.

In the following example, we show you how the APIM Lambda function dynamically applies different middleware based on the route configuration. This approach allows for flexible handling of authentication, client access restrictions, and request/response transformations. Here’s a quick breakdown of the key elements:

// If the route requires OIDC (OpenID Connect) authentication,
// add the OIDC authentication middleware to the route.
if route.Auth == "OIDC" {
    r.Use(middleware.OidcAuthenticator)
}
// If the route configuration specifies a list of allowed clients
// and the list is not empty, add a middleware to restrict access
// to only the specified clients.
if route.Allow.Clients != nil && len(route.Allow.Clients) != 0 {
    r.Use(middleware.AllowClients(route.Allow.Clients, cfg.Clients))
}
// Remove specific headers injected by the API Gateway
// to reduce exposure of internal details to downstream systems.
r.Use(middleware.RemoveGatewayHeaders)

// Add additional middleware for handling outbound logic.
// This could include retries, logging, or other outbound-specific functionality.
r.Use(outboundMiddlewares)
// Dynamically constructs and applies a chain of middlewares 
// based on the outbound configuration associated with the current request.
func outboundMiddlewares(next http.Handler) http.Handler {
    return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) {
        // Retrieve the outbound configuration from the request context.
        outbound, _ := r.Context().Value(selectedOutboundContext).(config.Outbound)

        // Initialize a slice to store the middlewares to be applied.
        middlewares := []func(http.Handler) http.Handler{}

        // Middleware to rewrite the HTTP request based on the outbound configuration.
        middlewares = append(middlewares, middleware.ProxyRequestRewrite(&outbound))

        // Add a middleware for mapping request data if specified in the outbound configuration.
        if len(outbound.Convert.Request) != 0 {
            middlewares = append(middlewares, middleware.RequestDataMapping(outbound.Convert.Request))
        }

        // Middleware to log the outbound response for monitoring or debugging purposes.
        middlewares = append(middlewares, middleware.OutboundResponseLog)

        // Add a middleware for mapping response data if specified in the outbound configuration.
        if len(outbound.Convert.Response) != 0 {
            middlewares = append(middlewares, middleware.ResponseDataMapping(outbound.Convert.Response))
        }

        // Add a middleware for modifying the response if a modification function is defined.
        if outbound.ModifyResponse != "" {
            f, ok := system.MODIFY[outbound.ModifyResponse]
            if ok {
                middlewares = append(middlewares, f())
            }
        }

        // Chain the constructed middlewares together and apply them to the request.
        chain := chi.Chain(middlewares...)
        chain.Handler(next).ServeHTTP(w, r)
    })
}

By using a middleware chain, you can customize how each request and response is processed on a per-route basis. This architecture not only keeps your code organized but also makes the API Gateway-integrated Lambda function far more adaptable to changing requirements. You can add or remove configurations from APIM portal as new use cases emerge—such as data transformations, custom logging, or additional security checks—without rewriting core logic.

  1. Configuration management: Administrators set up server-side and client-side settings, such as API Gateway parameters, authentication requirements, transformations, and more.
  2. Persistence:  DynamoDB stores these configurations, providing persistent data storage and auditing capabilities.
  3. Asynchronous resource provisioning: After administrators save configurations and release them from the APIM portal, APIM creates or updates AWS resources—such as API Gateway, Lambda functions, and AWS Identity and Access Management (IAM). Lambda runs these updates in the background, so administrators can continue working uninterrupted.

Runtime state

The runtime state includes the following elements:

A. Client request: Clients send requests to the APIM endpoint.

B. Routing to the correct gateway: APIM uses the URI prefix in the API mappings associated with custom domain names to route requests to the appropriate API gateway, as shown in the following figure. Each mapping defines a specific API, stage, and an optional path. When a request arrives, APIM checks the path and directs the request to the correct stage and API if it matches. Unmatched requests default to the mapping with no path defined.

C. APIM core processing: A Lambda function (APIM CORE) uses DynamoDB configurations to handle authentication, authorization, protocol conversion, field transformation, and routing.

D. Downstream service call: APIM forwards each request to the configured internal or external endpoint.

E. Logging and monitoring: API Gateway access logs and custom logs track requests in detail.

F. Alarm: Metrics and alarms detect anomalies and notify stakeholders. Use Amazon CloudWatch or self-hosted solutions such as ELK to enable real-time monitoring and alerting.

api-mapping

Conclusion

In this post, we’ve demonstrated how to build an enterprise API management (APIM) solution using Amazon API Gateway, AWS Lambda, Amazon DynamoDB, and other AWS services. We’ve also shown how APIM centralizes critical features—such as version management, security policies, and request/response transformations—to accommodate large-scale enterprise requirements.

You can use the APIM portal to store and manage configurations in DynamoDB, dynamically applying these settings to multiple API gateways without rewriting code. This approach ensures consistent governance across diverse client types and business scenarios, helping to keep APIs both secure and flexible.

Finally, you’ve seen how the APIM architecture unifies the management state and runtime state, streamlines administrative tasks, and provides end-to-end monitoring and alerting. By adopting these best practices, your enterprise can establish a robust, scalable, and secure API management foundation, all within a serverless paradigm.


About the Authors

Design patterns for implementing Hive Metastore for Amazon EMR on EKS

Post Syndicated from Avinash Desireddy original https://aws.amazon.com/blogs/big-data/design-patterns-for-implementing-hive-metastore-for-amazon-emr-on-eks/

In modern data architectures, the need to manage and query vast datasets efficiently, consistently, and accurately is paramount. For organizations that deal with big data processing, managing metadata becomes a critical concern. This is where Hive Metastore (HMS) can serve as a central metadata store, playing a crucial role in these modern data architectures.

HMS is a central repository of metadata for Apache Hive tables and other data lake table formats (for example, Apache Iceberg), providing clients (such as Apache Hive, Apache Spark, and Trino) access to this information using the Metastore Service API. Over time, HMS has become a foundational component for data lakes, integrating with a diverse ecosystem of open source and proprietary tools.

In non-containerized environments, there was typically only one approach to implementing HMS—running it as a service in an Apache Hadoop cluster. With the advent of containerization in data lakes through technologies such as Docker and Kubernetes, multiple options for implementing HMS have emerged. These options offer greater flexibility, allowing organizations to tailor HMS deployment to their specific needs and infrastructure.

In this post, we will explore the architecture patterns and demonstrate their implementation using Amazon EMR on EKS with Spark Operator job submission type, guiding you through the complexities to help you choose the best approach for your use case.

Solution overview

Prior to Hive 3.0, HMS was tightly integrated with Hive and other Hadoop ecosystem components. Hive 3.0 introduced a Standalone Hive Metastore. This new version of HMS functions as an independent service, decoupled from other Hive and Hadoop components such as HiveServer2. This separation enables various applications, such as Apache Spark, to interact directly with HMS without requiring a full Hive and Hadoop environment installation. You can learn more about other components of Apache Hive on the Design page.

In this post, we will use a Standalone Hive Metastore to illustrate the architecture and implementation details of various design patterns. Any reference to HMS refers to a Standalone Hive Metastore.

The HMS broadly consists of two main components:

  • Backend database: The database is a persistent data store that holds all the metadata, such as table schemas, partitions, and data locations.
  • Metastore service API: The Metastore service API is a stateless service that manages the core functionality of the HMS. It handles read and write operations to the backend database.

Containerization and Kubernetes offers various architecture and implementation options for HMS, including, running:

In this post, we’ll use Apache Spark as the data processing framework to demonstrate these three architectural patterns. However, these patterns aren’t limited to Spark and can be applied to any data processing framework, such as Hive or Trino, that relies on HMS for managing metadata and accessing catalog information.

Note that in a Spark application, the driver is responsible for querying the metastore to fetch table schemas and locations, then distributes this information to the executors. Executors process the data using the locations provided by the driver, never needing to query the metastore directly. Hence, in the three patterns described in the following sections, only the driver communicates with the HMS, not the executors.

HMS as sidecar container

In this pattern, HMS runs as a sidecar container within the same pod as the data processing framework, such as Apache Spark. This approach uses Kubernetes multi-container pod functionality, allowing both HMS and the data processing framework to operate together in the same pod. The following figure illustrates this architecture, where the HMS container is part of Spark driver pod.

HMS as sidecar container

This pattern is suited for small-scale deployments where simplicity is the priority. Because HMS is co-located with the Spark driver, it reduces network overhead and provides a straightforward setup. However, it’s important to note that in this approach HMS operates exclusively within the scope of the parent application and isn’t accessible by other applications. Additionally, row conflicts might arise when multiple jobs attempt to insert data into the same table simultaneously. To address this, you should make sure that no two jobs are writing to the same table simultaneously.

Consider this approach if you prefer a basic architecture. It’s ideal for organizations where a single team manages both the data processing framework (for example, Apache Spark) and HMS, and there’s no need for other applications to use HMS.

Cluster dedicated HMS

In this pattern, HMS runs in multiple pods managed through a Kubernetes deployment, typically within a dedicated namespace in the same data processing EKS cluster. The following figure illustrates this setup, with HMS decoupled from Spark driver pods and other workloads.

Cluster dedicated HMS

This pattern works well for medium-scale deployments where moderate isolation is enough, and compute and data needs can be handled within a few clusters. It provides a balance between resource efficiency and isolation, making it ideal for use cases where scaling metadata services independently is important, but complete decoupling isn’t necessary. Additionally, this pattern works well when a single team manages both the data processing frameworks and HMS, ensuring streamlined operations and alignment with organizational responsibilities.

By decoupling HMS from Spark driver pods, it can serve multiple clients, such as Apache Spark and Trino, while sharing cluster resources. However, this approach might lead to resource contention during periods of high demand, which can be mitigated by enforcing tenant isolation on HMS pods.

External HMS

In this architecture pattern, HMS is deployed in its own EKS cluster deployed using Kubernetes deployment and exposed as a Kubernetes Service using AWS Load Balancer Controller, separate from the data processing clusters. The following figure illustrates this setup, where HMS is configured as an external service, separate from the data processing clusters.

External HMS

This pattern suits scenarios where you want a centralized metastore service shared across multiple data processing clusters. HMS allows different data teams to manage their own data processing clusters while relying on the shared metastore for metadata management. By deploying HMS in a dedicated EKS cluster, this pattern provides maximum isolation, independent scaling, and the flexibility to operate and managed as its own independent service.

While this approach offers clear separation of concerns and the ability to scale independently, it also introduces higher operational complexity and potentially increased costs because of the need to manage an additional cluster. Consider this pattern if you have strict compliance requirements, need to ensure complete isolation for metadata services, or want to provide a unified metadata catalog service for multiple data teams. It works well in organizations where different teams manage their own data processing frameworks and rely on a shared metadata store for data processing needs. Additionally, the separation enables specialized teams to focus on their respective areas.

Deploy the solution

In the remainder of this post, you will explore the implementation details for each of the three architecture patterns, using EMR on EKS with Spark Operator job submission type as an example to demonstrate their implementation. Note that this implementation hasn’t been tested with other EMR on EKS Spark job submission types. You will begin by deploying the common components that serve as the foundation for all the architecture patterns. Next, you’ll deploy the components specific to each pattern. Finally, you’ll execute Spark jobs to connect to the HMS implementation unique to each pattern and verify the successful execution and retrieval of data and metadata.

To streamline the setup process, we’ve automated the deployment of common infrastructure components so you can focus on the essential aspects of each HMS architecture. We’ll provide detailed information to help you understand each step, simplifying the setup while preserving the learning experience.

Scenario

To showcase the patterns, you will create three clusters:

  • Two EMR on EKS clusters: analytics-cluster and datascience-cluster
  • An EKS cluster: hivemetastore-cluster

Both analytics-cluster and datascience-cluster serve as data processing clusters that run Spark workloads, while the hivemetastore-cluster hosts the HMS.

You will use analytics-cluster to illustrate the HMS as sidecar and cluster dedicated pattern. You will use all three clusters to demonstrate the external HMS pattern.

Source code

You can find the codebase in the AWS Samples GitHub repository.

Prerequisites

Before you deploy this solution, make sure that the following prerequisites are in place:

Set up common infrastructure

Begin by setting up the infrastructure components that are common to all three architectures.

  1. Clone the repository to your local machine and set the two environment variables. Replace <AWS_REGION> with the AWS Region where you want to deploy these resources.
git clone https://github.com/aws-samples/sample-emr-eks-hive-metastore-patterns.git
cd sample-emr-eks-hive-metastore-patterns
export REPO_DIR=$(pwd)
export AWS_REGION=<AWS_REGION>
  1. Execute the following script to create the shared infrastructure.
cd ${REPO_DIR}/setup
./setup.sh
  1. To verify successful infrastructure deployment, navigate to the AWS Management Console for AWS CloudFormation, select your stack, and check the Events, Resources, and Outputs tabs for completion status, details, and list of resources created.

You have completed the setup of the common components that serve as the foundation for all architectures. You will now deploy the components specific to each architecture and execute Apache Spark jobs to validate the successful implementation.

HMS in a sidecar container

To implement HMS using the sidecar container pattern, the Spark application requires setting both sidecar and catalog properties in the job configuration file.

  1. Execute the following script to configure the analytics-cluster for sidecar pattern. For this post, we stored the HMS database credentials into a Kubernetes Secret object. We recommend using Kubernetes External Secrets Operator to fetch HMS database credentials from AWS Secrets Manager.
cd ${REPO_DIR}/hms-sidecar
./configure-hms-sidecar.sh analytics-cluster
  1. Review the Spark job manifest file spark-hms-sidecar-job.yaml. This file was created by substituting variables in the spark-hms-sidecar-job.tpl template in the previous step. The following samples highlight key sections of the manifest file.
spec:
  driver:
  ...
    sidecars:
      # Hive Metastore Sidecar container
      - name: hive-metastore
        image: ${AWS_ACCOUNT_ID}.dkr.ecr.${AWS_REGION}.amazonaws.com/hive-metastore:latest
        env:
          # These settings configure metastore to use Amazon Postgres RDS as backend database, connecting to it via jdbc URL.
          - name: HIVE_METASTORE_DB_TYPE
            value: postgres
          - name: HIVE_METASTORE_DB_DRIVER
            value: org.postgresql.Driver
          - name: HIVE_METASTORE_DB_URL
            value: jdbc:postgresql://${HMS_RDS_PROXY_ENDPOINT}:5432/hivemetastore
          # The warehouse location is specified as an S3 bucket
          - name: HIVE_METASTORE_WAREHOUSE_LOC
            value: s3a://${S3_BUCKET_NAME}/warehouse
          - name: AWS_REGION
            value: ${AWS_REGION}
          # The database username and password are passed via environment variables. The password is retrieved from a Kubernetes secret
          - name: HIVE_METASTORE_DB_USER
            value: hive_metastore_user
          - name: HIVE_METASTORE_DB_PASSWORD
            valueFrom:
              secretKeyRef:
                name: hms-rds-password
                key: HIVE_METASTORE_DB_PASSWORD

Spark job configuration

spec:  
  sparkConf:
    # Hive Catalog properties
    # Sets spark to use Hive as the catalog for SQL operations
    spark.sql.catalogImplementation: "hive"
    # HMS is exposed on localhost:8080 since the sidecar runs in the same pod. Spark connects to the sidecar via this URI
    spark.hadoop.hive.metastore.uris: "thrift://localhost:9083"
    # The data location is set to S3 bucket
    spark.sql.warehouse.dir: "s3a://${S3_BUCKET_NAME}/warehouse"
    # Retrieve temporary AWS credentials by assuming a role using a web identity token
    spark.hadoop.fs.s3a.aws.credentials.provider: "com.amazonaws.auth.WebIdentityTokenCredentialsProvider"
    # Configure Spark to use S3A filesystem
    spark.hadoop.fs.s3a.impl: "org.apache.hadoop.fs.s3a.S3AFileSystem"

Submit the Spark job and verify the HMS as sidecar container setup

In this pattern, you will submit Spark jobs in analytics-cluster. The Spark jobs will connect to the HMS service running as a sidecar container in the driver pod.

  1. Run the Spark job to verify that the setup was successful.
kubectl apply -f spark-hms-sidecar-job.yaml
  1. Describe the sparkapplication object.
kubectl get sparkapplication -n emr
kubectl describe sparkapplication spark-hms-sidecar-job --namespace emr
  1. List the pods and observe the number of containers attached to the driver pod. Wait until the Status changes from ContainerCreating to Running (should take just a few seconds).
kubectl get pods -n emr
  1. View the driver logs to validate the output.
kubectl logs spark-hms-sidecar-job-driver --namespace emr
  1. If you encounter the following error, wait for a few minutes and rerun the previous command.
Error from server (BadRequest): container "spark-kubernetes-driver" in pod "spark-hms-sidecar-driver" is waiting to start: ContainerCreating
  1. After successful completion of the job, you see the following message in the logs. The tabular output successfully validates the setup of HMS as a sidecar container.
...
24/09/17 21:44:00 INFO metastore: Trying to connect to metastore with URI thrift://localhost:9083
24/09/17 21:44:00 INFO metastore: Opened a connection to metastore, current connections: 1
24/09/17 21:44:00 INFO metastore: Connected to metastore.
...
...
+-------+---+-------+---+
|pattern|id |name   |age|
+-------+---+-------+---+
|Sidecar|1 |Alice   |30 |
|Sidecar|2 |Bob     |25 |
|Sidecar|3 |Charlie |35 |
+-------+---+-------+---+

Cluster dedicated HMS

To implement HMS using a cluster dedicated HMS pattern, the Spark application requires setting up HMS URI and catalog properties in the job configuration file.

  1. Execute the following script to configure the analytics-cluster for cluster dedicated pattern.
cd ${REPO_DIR}/hms-cluster-dedicated
./configure-hms-cluster-dedicated.sh analytics-cluster
  1. Verify the HMS deployment by listing the pods and viewing the logs. No Java exceptions in the logs confirms that the Hive Metastore service is running successfully.
kubectl get pods --namespace hive-metastore
kubectl logs <HMS-PODNAME> --namespace hive-metastore
  1. Review the Spark job manifest file, spark-hms-cluster-dedicated-job.yaml. This file is created by substituting variables in the spark-hms-cluster-dedicated-job.tpl template in the previous step. The following sample highlights key sections of the manifest file.
spec: 
  sparkConf:
    # Hive Catalog properties
    # Sets spark to use Hive as the catalog for SQL operations
    spark.sql.catalogImplementation: "hive"
    # HMS is running in a pod and we can connect to it in the same EKS cluster via this URI
    spark.hadoop.hive.metastore.uris: "thrift://hive-metastore-svc.hive-metastore.svc.cluster.local:9083"
    # The data location is set to S3 bucket
    spark.sql.warehouse.dir: "s3a://${S3_BUCKET_NAME}/warehouse"
    # Retrieve temporary AWS credentials by assuming a role using a web identity token
    spark.hadoop.fs.s3a.aws.credentials.provider: "com.amazonaws.auth.WebIdentityTokenCredentialsProvider"
    # Configure Spark to use S3A filesystem
    spark.hadoop.fs.s3a.impl: "org.apache.hadoop.fs.s3a.S3AFileSystem"

Submit the Spark job and verify the cluster dedicated HMS setup

In this pattern, you will submit Spark jobs in analytics-cluster. The Spark jobs will connect to the HMS service in the same data processing EKS cluster.

  1. Submit the job.
kubectl apply -f spark-hms-cluster-dedicated-job.yaml -n emr
  1. Verify the status.
kubectl get sparkapplication -n emr
kubectl describe sparkapplication spark-hms-cluster-dedicated-job --namespace emr
  1. Describe driver pod and observe the number of containers attached to the driver pod. Wait until the status changes from ContainerCreating to Running (should take just a few seconds).
kubectl get pods -n emr
  1. View the driver logs to validate the output.
kubectl logs spark-hms-cluster-dedicated-job-driver --namespace emr
  1. After successful completion of the job, you should see the following message in the logs. The tabular output successfully validates the setup of cluster dedicated HMS.
...
24/09/17 21:44:00 INFO metastore: Trying to connect to metastore with URI thrift://hive-metastore-svc.hive-metastore.svc.cluster.local:9083
24/09/17 21:44:00 INFO metastore: Opened a connection to metastore, current connections: 1
24/09/17 21:44:00 INFO metastore: Connected to metastore.
...
...
+-----------------+---+-------+---+
|pattern          |id |name   |age|
+-----------------+---+-------+---+
|Cluster Dedicated|1  |Alice  |30 |
|Cluster Dedicated|2  |Bob    |25 |
|Cluster Dedicated|3  |Charlie|35 |
+-----------------+---+-------+---+

External HMS

To implement an external HMS pattern, the Spark application requires setting up an HMS URI for the service endpoint exposed by hivemetastore-cluster.

  1. Execute the following script to configure hivemetastore-cluster for External HMS pattern.
cd ${REPO_DIR}/hms-external
./configure-hms-external.sh
  1. Review the Spark job manifest file spark-hms-external-job.yaml. This file is created by substituting variables in the spark-hms-external-job.tpl template during the setup process. The following sample highlights key sections of the manifest file.
spec:
  sparkConf:
    # Hive Catalog properties
    # Sets spark to use Hive as the catalog for SQL operations
    spark.sql.catalogImplementation: "hive"
    # HMS is running in a cluster and we can connect to it in the EKS cluster via this URI
    spark.hadoop.hive.metastore.uris: "thrift://${HMS_URI_ENDPOINT}:9083"
    # The data location is set to S3 bucket
    spark.sql.warehouse.dir: "s3a://${S3_BUCKET_NAME}/warehouse"
    # Retrieve temporary AWS credentials by assuming a role using a web identity token
    spark.hadoop.fs.s3a.aws.credentials.provider: "com.amazonaws.auth.WebIdentityTokenCredentialsProvider"
    # Configure Spark to use S3A filesystem
    spark.hadoop.fs.s3a.impl: "org.apache.hadoop.fs.s3a.S3AFileSystem"

Submit the Spark job and verify the HMS in a separate EKS cluster setup

To verify the setup, submit Spark jobs in analytics-cluster and datascience-cluster. The Spark jobs will connect to the HMS service in the hivemetastore-cluster.

Use the following steps for analytics-cluster and then for datascience-cluster to verify that both clusters can connect to the HMS on hivemetastore-cluster.

  1. Run the spark job to test the successful setup. Replace <CONTEXT_NAME> with Kubernetes context for analytics-cluster and then for datascience-cluster.
kubectl config use-context <CONTEXT_NAME>
kubectl apply -f spark-hms-external-job.yaml -n emr
  1. Describe the sparkapplication object.
kubectl get sparkapplication spark-hms-external-job -n emr
kubectl describe sparkapplication spark-hms-external-job --namespace emr
  1. List the pods and observe the number of containers attached to the driver pod. Wait until the status changes from ContainerCreating to Running (should take just a few seconds).
kubectl get pods -n emr
  1. View the driver logs to validate the output on the data processing cluster.
kubectl logs spark-hms-external-job-driver --namespace emr
  1. The output should look like the following. The tabular output successfully validates the setup of HMS in a separate EKS cluster.
After successful completion of the job, you should be able to see the below message in the logs.
...
24/09/17 21:44:00 INFO metastore: Trying to connect to metastore with URI  thrift://k8s-hivemeta-hmsexter-xxxxxx.elb.us-east-1.amazonaws.com:9083
24/09/17 21:44:00 INFO metastore: Opened a connection to metastore, current connections: 1
24/09/17 21:44:00 INFO metastore: Connected to metastore.
...
...
+--------+---+-------+---+
|pattern |id |name   |age|
+--------+---+-------+---+
|External|1  |Alice  |30 |
|External|2  |Bob    |25 |
|External|3  |Charlie|35 |
+--------+---+-------+---+

Clean up

To avoid incurring future charges from the resources created in this tutorial, clean up your environment after you’ve completed the steps. You can do this by running the cleanup.sh script, which will safely remove all the resources provisioned during the setup.

cd ${REPO_DIR}/setup
./cleanup.sh

Conclusion

In this post, we’ve explored the design patterns for implementing the Hive Metastore (HMS) with EMR on EKS with Spark Operator, each offering distinct advantages depending on your requirements. Whether you choose to deploy HMS as a sidecar container within the Apache Spark Driver pod, or as a Kubernetes deployment in the data processing EKS cluster, or as an external HMS service in a separate EKS cluster, the key considerations revolve around communication efficiency, scalability, resource isolation, high availability, and security.

We encourage you to experiment with these patterns in your own setups, adapting them to fit your unique workloads and operational needs. By understanding and applying these design patterns, you can optimize your Hive Metastore deployments for performance, scalability, and security in your EMR on EKS environments. Explore further by deploying the solution in your AWS account and share your experiences and insights with the community.


About the Authors

Avinash Desireddy is a Cloud Infrastructure Architect at AWS, passionate about building secure applications and data platforms. He has extensive experience in Kubernetes, DevOps, and enterprise architecture, helping customers containerize applications, streamline deployments, and optimize cloud-native environments.

Suvojit Dasgupta is a Principal Data Architect at AWS. He leads a team of skilled engineers in designing and building scalable data solutions for AWS customers. He specializes in developing and implementing innovative data architectures to address complex business challenges.

Realizing twelve-factors with the AWS Well-Architected Framework

Post Syndicated from Michael Phorn original https://aws.amazon.com/blogs/architecture/realizing-twelve-factors-with-the-aws-well-architected-framework/

Organizations that are interested in improving their development velocity that follow the principles of the twelve-factor app might find benefits in understanding how to realize those concepts on Amazon Web Services (AWS). In this post, I will help you correlate the twelve-factors app concepts as you architect solutions on AWS.

Twelve-factors

Let’s start with a quick recap of twelve-factors. The Twelve-Factor App was published in 2011 by Adam Wiggins as a collaboration between developers at Heroku. He published it at a time when developers were shifting from a paradigm of writing software-as-a-service (SaaS) applications in their own cloud environments to having the applications hosted on a cloud provider, such as AWS. Their intent was to provide “a broad set of conceptual solutions” for building applications that were portable and resilient. The principles centered around reducing the software lifecycle burden, including application introduction, maintenance and operations, through sunsetting. These principles were captured in the following 12 factors:

  1. Codebase
  2. Dependencies
  3. Config
  4. Backing services
  5. Build, release, run
  6. Processes
  7. Port binding
  8. Concurrency
  9. Disposability
  10. Development and production environment parity
  11. Logs
  12. Admin process

These principles are portable and resilient application best practices.

At AWS, we have the Well-Architected Framework to capture cloud and architecture best practices, which contains similar practices to twelve-factors. The Framework comes from years of AWS Solutions Architect collective experience of building solutions across business verticals and use cases. The results are architectures that support secure, high-performing, resilient, and cost-effective systems in the cloud. If you’re responsible for the underlying infrastructure or the application, the Framework helps you, the CTO, the architect, the developer, or operations team member, understand the benefits and trade-offs of decisions that have to be made.

A brief history of the AWS Well-Architected Framework

AWS published the first version of the Framework in 2012, and we released the AWS Well-Architected Framework whitepaper in 2015. Following the initial introduction, we added the Operational Excellence pillar in 2016 and released pillar-specific whitepapers and AWS Well-Architected Lenses in 2017. The following year, the AWS Well-Architected Tool was launched.

While twelve-factors focuses on application characteristics, the AWS Well-Architected Framework provides architectural guidance. When your architecture undergoes a Well-Architected review, you can meet the guidance for a twelve-factors application more easily. With some factors, the Framework helps the application developer delegate some responsibility from the application to the infrastructure. Both frameworks aim to help you deliver applications and services that are robust, scalable, and cloud centered. The AWS Well-Architected Framework helps you reinforce these mechanisms.

The six pillars of the AWS Well-Architected Framework

Let’s explore the six pillars of the AWS Well-Architected Framework, what each aims to achieve, and where the twelve-factors concepts intersect with AWS guidance.

The following figures shows the twelve factors and how they map to processes in AWS, which are described in this section.

1. Operational excellence

The operational excellence pillar helps you review your organization’s ability to support development and run workloads efficiently. You can use the topics in this pillar to evaluate how you operate your solutions. The pillar guides you through inspection of organizational structure, inspection of your mechanisms, and identification of obstacles and roadblocks that might slow your ability to innovate. The results include a feedback loop of continuous improvement for operating the infrastructure and solutions.

The factors you capture through operational excellence are codebase (I) and development and production environment parity (X). Codebase prescribes that there is exactly one codebase used to deploy everywhere, which echoes the purpose of reducing the operational burden of maintaining your software. The argument for a single code base is for consistency, traceability, and efficiency across a unified development lifecycle. The second factor is development and production environment parity, which encourages developers to create smaller but more frequent deployments. It also encourages developers to maintain parity not just of the core software, but also the backing services between environments. Parity of environments is conducive to smoother development and deployment processes. Additionally, this parity helps developers catch issues in a non-production environment more consistently.

AWS services that can help you achieve operational excellence are AWS CodeConnections, AWS CodePipeline, AWS CloudFormation, AWS Systems Manager, Amazon CloudWatch, AWS Config, AWS CloudTrail, Amazon EventBridge, AWS X-Ray, AWS Organizations, AWS Control Tower, AWS Trusted Advisor, AWS Service Catalog, AWS Proton, Amazon CodeGuru (Preview), AWS Lambda, Amazon Simple Queue Service (Amazon SQS), Amazon Simple Notification Service (Amazon SNS), and AWS StepFunctions

2. Security

The security pillar describes how to use AWS Cloud technologies to protect data, systems, and assets that improve your security posture. At AWS, we advocate the shared responsibility model, which applies to the security pillar. AWS is responsible for providing a secure environment for managing and operating your systems and solutions, but it is your responsibility to implement those best practices in the context of your requirements. The security pillar describes best practices such as reviewing how you manage identities for people and machines, which helps you store secrets securely.

The config (III) factor can be mapped to the security pillar, which advises you to store variables and items that depend upon the environment as environment variables. This allows you to move between deployments without having to update your code. Configuration settings such as database connection strings, API keys, credentials, and other sensitive information should be separated from the application code. At AWS, we provide services that can be used to securely meet this requirement, including AWS Secrets ManagerAWS Systems Manager Parameter Store, AWS Certificate Manager, and AWS Key Management Service (KMS).

AWS services that can help you achieve security are AWS Identity and Access Management (IAM), Amazon GuardDuty, AWS Shield, AWS Web Application Firewall (WAF), Amazon Inspector, AWS CloudHSM, Amazon Macie, AWS Security Hub, AWS Config, AWS CloudTrail, Amazon VPC (Virtual Private Cloud), AWS Direct Connect, Amazon Cognito, AWS Firewall Manager, AWS Network Firewall, and AWS IAM Access Analyzer.

3. Reliability

The reliability pillar encompasses the ability of a workload to perform its intended function correctly and consistently when it’s expected to. Reliability means that your architecture and systems:

  • Appropriately scale resources to meet demands
  • Mitigate disruptions caused by misconfiguration or transient network issues
  • Recover when disruptions do occur

Automation of scaling and recovery are best practices within the reliability pillar.

Because twelve-factors helps developers deliver a reliable application, multiple factors are categorized under the reliability pillar of the AWS Well-Architected Framework. Backing services (IV) explains that you should have flexibility for integrating services. This way, when your system experiences issues with availability, the application can replace the troubled service without code changes. You should choose the right resource that provides scalability while optimizing costs. Dependencies (III) describes that applications declare and isolate dependencies to become modular and self-contained. This speeds up recovery by simplifying the setup for handlers of the application code. Applications that adhere to the processes (VI) factor run as a collection of stateless processes to support scaling. This is equivalent to creating microservices that can scale up or down depending upon the workload or bring in additional instances when one fails. Disposability (IX) suggests that an application’s processes can be started and stopped rapidly, which makes the application resilient to failures and capable of being adapted to elastically scale.

AWS services that can help you achieve reliability are Amazon EC2 Auto Scaling, Elastic Load Balancing (ELB), Amazon RDS Multi-AZ, Amazon Simple Storage Service (Amazon S3), AWS CloudFormation, Amazon Route53, AWS Shield, AWS Backup, Amazon CloudWatch, AWS Systems Manager, AWS Global Accelerator, Amazon Aurora, AWS Lambda, Amazon DynamoDB, and AWS Transit Gateway.

4. Performance efficiency

The principles under the performance efficiency pillar focus on using computing resources to build architectures on AWS that efficiently deliver sustained performance as demand changes and technologies evolve. Topics in this pillar include simplifying the consumption of technologies that align with your goals, the ability to go global in minutes, and reducing the time and effort needed to deliver a service.

The concurrency (VIII) factor prioritizes management of processes, which should be stateless and allow for horizontal scaling, promoting performance efficiency. The backing services (IV) factor also falls under this category because it dictates flexibility in integration. This flexibility enables the application to maximize performance by using the right resource that meets scalability and performance requirements.

AWS services that can help you achieve performance efficiency are Amazon Elastic Compute Cloud (Amazon EC2), Amazon EC2 AutoScaling, Amazon Elastic Block Store (Amazon EBS), Amazon S3, Amazon Aurora, Amazon DynamoDB, Amazon ElastiCache, Amazon CloudFront,Application Auto ScalingElastic Load Balancing (ELB), AWS Lambda, Amazon API GatewayAWS Step Functions, Amazon SQS, Amazon Kinesis, AWS Global Accelerator, Amazon Aurora, AWS X-Ray, Amazon CloudWatch, and AWS Compute Optimizer.

5. Cost optimization

The cost optimization pillar provides guidance for the architecture’s ability to operate systems and deliver the business value at the lowest price point. The cost optimization reviews help you avoid unnecessary costs, analyze and attribute expenditure, and use appropriate pricing models.

The relationship of the build, release, run (V) factor advocates for the process separation and strict discipline around efficient handling of application deployments. This aligns to the cost optimization pillar because cost effective operations are typically a result of well-designed processes and mechanisms. AWS services that can support the build, release, run factor are, AWS CodeBuild and AWS CodeDeploy.

Other AWS services that can help you with cost optimization are AWS Cost Explorer, AWS Budgets, AWS Data Exports, AWS Trusted Advisor, AWS Compute Optimizer, EC2 Spot Instances, AWS Savings Plans, Amazon S3 Intelligent-Tiering, AWS Lambda, Amazon Aurora, Application Auto Scaling, AWS Organizations, AWS Resource Groups, Tag Editor, AWS Marketplace, AWS License Manager, AWS Glue, and Amazon Athena.

6. Sustainability

The sustainability pillar focuses on minimizing the environmental impact of running workloads in the cloud. Topics in this include reviewing the lifecycle of your data and retention policies as a methodology to use only what is needed.

The disposability (IX) factor is aligned to sustainability because it highlights an application’s ability to rapidly start and shut down at a moment’s notice. This provides agility and optimized use of resources during the life of the application.

AWS services that can help you achieve sustainability are AWS Customer Carbon Footprint ToolAmazon EC2 AutoScalingAWS Lambda, Amazon EC2 Spot Instances, Amazon EBS gp3 volumes, Amazon S3 Intelligent-Tiering, Amazon S3 Lifecycle configurations, AWS Graviton processors, Amazon Aurora Serverless, Amazon RDS Multi-AZ deployments, AWS Compute Optimizer, AWS Well Architected Tool, and Amazon CloudWatch.

Remaining factors

Port binding, logs, and admin processes aren’t specifically categorized into the pillars of the AWS Well-Architected Framework. However, these factors can be addressed as an essential part of the services that AWS delivers.

The seventh factor: Port binding

The port binding factor says that an application should be bound to a specific port when it’s hosted as a web application with the intention of making the application completely self-contained. In the context of AWS, we offer you different ways to achieve this principle, which are dependent upon the way your application is deployed on AWS. When implementing port binding on AWS, we offer features such as security, service discovery, and dynamic port mapping to simplify and secure your applications through services like Amazon EC2, Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), AWS Elastic Beanstalk, AWS App Runner.

The eleventh factor: Logs

The logs factor dictates that an application should treat its running process as an event stream out to files that are managed completely by the execution environment. AWS offers many types of logging to capture different aspects of your application and the supporting infrastructure. CloudWatch is a centralized logging management service that monitors, stores, and provides access to log files from AWS services. For more detail, see AWS services for logging and monitoring.

The twelfth factor: Admin processes

The admin processes factor advises application developers to perform administrative tasks in an isolated manner to minimize the impact on the main application. At AWS, this factor is realized as a separation of the control plane and the data plane. The control plane is responsible for managing, configuring, and controlling the network or system infrastructure, while the data plane is responsible for the handling the actual user data or traffic. This separation is an inherent part of AWS services. We believe this separation allows AWS to deliver services that are scalable, highly available, secure, and efficient.

Applying the AWS Well-Architected Framework

The Framework shouldn’t be treated as a checklist that you review after development is complete. Instead, a review should be explored during the design phase to help you learn and apply architectural best practices. By the end of development, architects should have built a solution that facilitates faster, lower-risk service building and deployment. The Framework is not a static document, and as AWS evolves, architects continue to learn from working with customers and refine the definition of well-architected.

Conclusion

If you are familiar with twelve-factors or want to develop a twelve-factors app on AWS, read more about the AWS Well-Architected Framework. Consider starting a review project on your own to explore the detailed questions underneath each category or if you have specific workload that you’re already working on. You can use one of the many AWS Well-Architected Tool lenses to focus on applying these best practices to the services that you’re using. To get started on a lens review, see AWS Well-Architected Tool, which is accessible at no charge through the AWS Management Console.


About the author

Create a serverless custom retry mechanism for stateless queue consumers

Post Syndicated from Kaizad Wadia original https://aws.amazon.com/blogs/architecture/create-a-serverless-custom-retry-mechanism-for-stateless-queue-consumers/

Serverless queue processors like AWS Lambda often exist in architectures where they pull messages from queues such as Amazon Simple Queue Service (Amazon SQS) and interact with downstream services or external APIs in a distributed architecture. Robust retry approaches are necessary to provide reliable message processing due to the susceptibility of these downstream services to short-term outages or throttling. This often requires implementing special retry logic with features like dead-letter queues (DLQs) and exponential backoff to handle these cases gracefully, making sure that the downstream systems don’t get overwhelmed by too many retries.

In this post, we propose a solution that handles serverless retries when the workflow’s state isn’t managed by an additional service.

Solution overview

Some custom retry logic is required when Lambda functions interact with downstream services after consuming messages from SQS queues. This strategy involves the usage of Amazon EventBridge Scheduler and code in Lambda. The core concept is to implement a robust retry mechanism for handling failed message processing attempts using an EventBridge scheduler. When a Lambda function encounters a problem while processing a message, it triggers a specific error. Upon catching this error in a catch block, the function generates an EventBridge schedule. As a result, the message is sent back to the SQS queue and will be available for processing again at a specified future time.

In this approach, the retry mechanism can have a fine-grained level of control over the retry timing that might also support various techniques, including exponential backoff and linear retry intervals. This approach separates the retry logic from the code to process the message itself, making the Lambda function performant. Along with handling messages when all retries are exhausted, this solution interfaces with a DLQ to keep such messages separate from the main queue.

The following diagram illustrates the solution architecture.

The error handling and retry choice logic in the Lambda function code form the basis for how this custom retry mechanism is implemented. If there is an error while processing the message, the function raises a specific exception. Raising the exception then initiates the retry flow. A try-catch block catches this exception and calls a function that interfaces with the EventBridge Scheduler API to build a custom schedule. To configure the schedule, we include the destination SQS queue and the intended timestamp when the message is meant to be retried. We can change the delay with some code modifications depending on a number of parameters, such as error type, number of prior retries, or other custom backoff schemes.

As part of this approach, we use SQS message attributes for idempotency and to track retries. On each retry, the function adds the new timestamp to an array in the message body. If the function consumes the message more times than the maximum retry limit (determined by the array of retry attempts) it sends the message to the DLQ without rescheduling.

The solution also involves the integration of a DLQ so that it doesn’t keep messages in the main processing queue and be retried forever. The Lambda function will register messages with the DLQ in case of either exceeding the maximum retry limit or when certain error scenarios require it to stop early. This queue keeps all communications that have failed until such a time they can be manually reviewed, reprocessed, or even corrected.

Considerations and best practices

There are a few key factors to keep in mind while putting this custom retry system into practice. One aspect is handling partial failures, that is, processing where only part of the steps are complete. In such cases, we could use some form of compensating action or rollback to maintain consistency in data and avoid discrepancies downstream of the queue consumer.

Another crucial factor is controlling retry limits. Although the system design allows for variable retry limits, we must balance resource usage and resilience. Too many retries might cause higher costs and lead to slowdowns or service degradation. That is why we recommend that appropriate retry limits are set, considering probable failure rates, SLAs, and business consequences of failures.

We must also consider that EventBridge Scheduler has a granularity of 1 minute, and there is additional latency between the queue and the function, so the mechanism will not be completely precise. In principle, the scheduler sets the minimum time before which the message can be processed, making sure the Lambda function adheres to the rate limits at a minimum. This could also result in additional delays, so the mechanism would need to be adjusted for time-sensitive applications to account for these delays.

Because the solution might deal with variable volumes of messages and processing loads, scaling issues are also important. For example, the Lambda concurrency and retention period for the queue represent resource configurations we should monitor and adjust for optimal performance and cost.

Finally, we need to consider security as part of the solution. If the downstream service runs in a virtual private cloud (VPC), we would also need to place the Lambda function in the VPC. In this case, we would need to access EventBridge Scheduler through AWS PrivateLink, which enables secure and performant access to services from within a VPC.

Additionally, it is important to implement the AWS Identity and Access Management (IAM) roles (mainly the Lambda function role) with the principal of least privilege, which gives it access to create the EventBridge schedule (and iam:PassRole to give the scheduler the required permissions) as well as pass the scheduler’s IAM role to it. The scheduler’s role only needs permission to place a message into the source queue. We also need to give the function access to place a message in the DLQ and receive messages from the source queue.

Monitoring and troubleshooting

The custom retry mechanism demands efficient monitoring and debugging. With that in mind, we might view various behaviors of the system and identify potential problems by using Amazon CloudWatch logs and metrics.

The number of invocations of Lambda functions, related error rates, runtimes, and use of DLQ are the key indicators that we should monitor. It would be worth setting up alarms in CloudWatch to send an alert or initiate automated actions when the Lambda function’s metrics surpass certain predetermined thresholds. By doing this, we proactively detect and resolve certain issues pertaining to the function.

Also, we can examine logs of the Lambda function for certain error situations, retry patterns, or problems with the downstream services or with the retry logic itself. We can place logging lines judiciously in the function code to record pertinent information, including message attributes, retry attempts, and error details.

Future enhancements

There are some improvements we could consider to enhance the capabilities and flexibility of the suggested approach even further, which provides a foundation to customize retry mechanisms.

A possible improvement would be to introduce dynamic retry intervals depending on the conditions of a downstream service or kinds of errors. Instead of being based on predefined backoff schemes, the system might dynamically adjust the retry intervals based on specific error types detected or in-service health monitoring in real time. This concept’s principal disadvantage is additional complexity, which might cause the failure of the retry process itself.

Another potential enhancement is the integration of the system with external configuration services such as Amazon DynamoDB or Parameter Store, a capability of AWS Systems Manager. That way, we can handle the retry configurations centrally and dynamically to provide ease of maintenance and modification in retry strategies without having to redeploy the Lambda function code.

It would also be possible to build in advanced error analysis and reporting into the system. The system would then have the potential to provide key insights for root cause analysis and proactive remediation through comprehensive reporting, patterns of errors analyzed, and failures correlated with downstream service health.

Conclusion

It is often challenging to build scalable, robust serverless applications that might need to talk with external services. However, the proposed solution using Lambda, Amazon SQS, and EventBridge Scheduler brings a simple yet effective solution to implement customized retry mechanisms. It gives the developer fine-grained control over the retry interval, supports scenarios such as exponential backoff, and works seamlessly with DLQs for persisting failures and EventBridge Scheduler for delayed retries of messages. The mechanism can also be reused more broadly for stateless queue consumers, not only for Lambda functions. This pattern enables developers to implement robust, fault-tolerant serverless systems that handle disruptions in downstream services gracefully.


About the Author

Top Architecture Blog Posts of 2024

Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2024/

Well, it’s been another historic year! We’ve watched in awe as the use of real-world generative AI has changed the tech landscape, and while we at the Architecture Blog happily participated, we also made every effort to stay true to our channel’s original scope, and your readership this last year has proven that decision was the right one.

AI/ML carries itself in the top posts this year, but we’re also happy to see that foundational topics like resiliency and cost optimization are still of great interest to our audience.

(By the way, if you were hoping for more AI/ML content, head on over to our sister channel, the AWS Machine Learning Blog!).

Without further ado, here are our top posts from 2024!

#10 Deploy Stable Diffusion ComfyUI on AWS elastically and efficiently

This post helps you get started using ComfyUI, and was so successful that we followed it up later in the year with How to build custom nodes workflow with ComfyUI on EKS!

Architecture for deploying stable diffusion on ComfyUI

Figure 1. Architecture for deploying stable diffusion on ComfyUI

#9 Let’s Architect! Designing Well-Architected systems

In keeping with Let’s Architect! series, we have our first of three favorites for the year. This set of resources helps you apply Well-Architected standards in practice.

Let's Architect

Figure 2. Let’s Architect

#8 Let’s Architect! Learn About Machine Learning on AWS

As I said, Let’s Architect! has a winning series, and they’ve got a finger on the pulse of the tech world. This post about machine learning showcases some of the most exciting things happening at AWS.

Let's Architect

Figure 3. Let’s Architect

If you’re more interested in generative AI, you can also take a look at another post from 2024: Let’s Architect! GenAI

#7 Creating an organizational multi-Region failover strategy

Preparedness is another common theme in this year’s favorites. Michael, John, and Saurabh are well-versed in multi-Region architecture, and they’re here to share some strategies to contain failure impact.

When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

Figure 4. When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

#6 Building a three-tier architecture on a budget

Let’s talk cost optimization. This post about a three-tier architecture that relies on the AWS Free Tier is a must-read for anyone looking for tips to help them avoid unnecessary costs (and that’s everyone).

Example of a three-tier architecture on AWS

Figure 5. Example of a three-tier architecture on AWS

#5 Announcing updates to the AWS Well-Architected Framework guidance

As usual, Haleh & team are pros at making sure the Well-Architected Framework is current and relevant. Take a look at the enhanced and expanded guidance in all six pillars.

Well-Architected logo

Figure 6. Well-Architected logo

#4 Let’s Architect! Serverless developer experience in AWS

One more winning post from Luca, Federica, Vittorio, and Zamira! This collection of developer resources includes new ideas in AWS Lambda, Amazon Q Developer, and Amazon DynamoDB.

Let's Architect

Figure 7. Let’s Architect

#3 London Stock Exchange Group uses chaos engineering on AWS to improve resilience

This post from April 1 was not an April Fool’s joke! See how LSEG designed failure scenarios to test their resilience and observability.

Chaos engineering pattern for hybrid architecture (3-tier application)

Figure 8. Chaos engineering pattern for hybrid architecture (3-tier application)

#2 Achieving Frugal Architecture using the AWS Well-Architected Framework Guidance

Frugality AND Well-Architected? What a winning combo! This post, inspired by the 2023 re:Invent keynote, outlines the seven laws of Frugal Architecture.

Well-Architected logo

Figure 9. Well-Architected logo

#1 How an insurance company implements disaster recovery of 3-tier applications

And finally, our number one post of the year! Amit and Luiz showcase a customer solution with real-world applications that builds on the guidelines of other posts in this list! Well done!

The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Figure 10. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Thank you!

As always, thanks to our contributors for their dedication and desire to share, and to you, our readers! We would be nothing with you. Literally.

For other top post lists, see our Top 10 and Top 5 posts from previous years.

TVS Supply Chain Solutions built a file transfer platform using AWS Transfer Family for AS2 for B2B collaboration

Post Syndicated from Suresh Kanniappan original https://aws.amazon.com/blogs/architecture/tvs-supply-chain-solutions-built-a-file-transfer-platform-using-aws-transfer-family-for-as2-for-b2b-collaboration/

TVS Supply Chain Solutions (TVS SCS), promoted by the erstwhile TVS Group and now part of the $3 billion TVS Mobility Group, is an India-based multinational company who pioneered the development of the supply chain solutions market in India.

For the last 2 decades, it has provided supply chain management services to customers in the automotive, consumer goods, defense, and utility sectors in India, the United Kingdom, Europe, and the US. It has a presence in 26 countries with over 17,000 employees and provides services to 78 global Fortune 500 companies. The company went public in 2023.

To meet its customers’ compliance requirements, TVS SCS sought a reliable file transfer solution supporting Applicability Statement 2 (AS2), a business-to-business (B2B) messaging protocol. This post describes how TVS SCS built a secure file transfer platform using AWS Transfer Family for AS2 to exchange Electronic Data Interchange (EDI) documents with their B2B customers in the logistics industry.

Business use case

Several end customers in the manufacturing sector mandated the exchange of EDI documents through the AS2 protocol over the internet. To address this requirement while maintaining manageability, security, and scalability, TVS SCS implemented a file transfer platform on AWS.

TVS SCS serves end customers in the manufacturing sector who require supply chain solutions between various locations:

  • Source – Plants, warehouses, technology
  • Destination – OEM vendors, plants, dealers

The process involves the following steps:

  1. The end customer sends a booking request document (booking fact) to TVS SCS.
  2. TVS SCS and the end customer exchange a series of EDI documents.
  3. TVS SCS must acknowledge, process, and update the end customer upon receipt of each EDI document.

TVS SCS built a file transfer platform using Transfer Family with AS2 configuration to achieve the following:

  • Securely exchange EDI documents with end customers
  • Provide continuous notification using Message Disposition Notifications (MDNs)

The following diagram illustrates the end-to-end business process (requisition, sourcing, purchase orders, receiving, and invoicing) between TVS SCS and an end customer using the AS2 protocol.

End to end business process

Why the cloud?

TVS SCS chose AWS to build their AS2-compliant file transfer platform for three key reasons:

  • Data location – All relevant data (such as order creation and customer details) already resides in AWS
  • Infrastructure management – AWS addresses challenges in the following areas:
    • Maintaining highly available and scalable infrastructure
    • Maintaining correct AS2 system interoperability with trading partners
    • Meeting compliance requirements
  • Versatility for non-AS2 customers – TVS SCS uses multiple scalable and fully managed AWS services to build customized APIs and webhooks for customers not using AS2

This cloud-based approach allows TVS SCS to focus on their core business while AWS handles the complexities of secure, compliant, and scalable file transfer infrastructure.

Why Transfer Family and AS2?

AS2 is a B2B messaging protocol commonly used for exchanging EDI documents securely with integrity control according to the EDIFACT standard, reliably, and cost-effectively over the internet using the HTTP and HTTPS protocols. B2B integration over the AS2 protocol can be challenging, such as with trading partner onboarding, AS2 EDI integration, firewall configuration, certificate maintenance, and high licensing costs for commercial AS2 solutions.

By choosing Transfer Family with AS2 configuration, TVS SCS addresses these challenges and gains several advantages:

  • Simplified partner onboarding
  • Managed infrastructure, reducing maintenance overhead
  • Built-in security features
  • Flexible scaling to meet changing business needs
  • Pay-as-you-go pricing model

Solution overview

The following diagram shows the relationship between the AS2 objects involved in the inbound and outbound processes.

Relationship between the AS2 objects

The following diagram illustrates the solution architecture with AWS services.

Solution Architecture

For step-by-step instructions about creating an AS2 server using Transfer Family, refer to Create an AS2 server using the Transfer Family console.

The allowlisted IP address of the end-customer AS2 server is allowed to communicate with Transfer Family for AS2 on AWS. The customer sends the EDI document through Transfer Family, and the EDIs are stored in Amazon Simple Storage Service (Amazon S3). The business logic is implemented in AWS Lambda functions to read the EDI documents, process them, and update customers. AWS B2B Data Interchange, a fully managed service for automating EDI document transformation, can be considered as a complementary or alternative solution for EDI processing. There are two Lambda functions created: one handles truck booking using NodeJS, and the other handles outbound file transfer (from Amazon S3 to the AS2 server) using Python 3.2.

This architecture enables TVS SCS to securely and efficiently manage the EDI document flow, from receipt through processing and outbound transfer, using scalable and serverless AWS services. The solution provides a compliant and cost-effective approach to B2B data exchange with customers and partners.

Prerequisites

For the prerequisites to configure Transfer Family with AS2, see Configuring AS2. To learn more about the security features in Transfer Family, see Security in AWS Transfer Family.

End customer to TVS SCS communication workflow

The following diagram illustrates the step-by-step process of a truck booking request from an end customer to TVS SCS using AWS services.

End customer to TVS SCS communication workflow

This streamlined workflow demonstrates how TVS SCS uses AWS services to efficiently handle truck booking requests from customers:

  1. The customer initiates a truck booking by sending a booking fact EDI to TVS SCS. The EDI contains details like customer name, date, source location, destination location, and more.
  2. The signed and encrypted booking fact EDI is sent as an inbound HTTP AS2 payload to Transfer Family through the internet.
  3. Transfer Family writes the booking fact EDI to the S3 bucket.
  4. TVS SCS confirms receipt of the booking fact EDI either through the inline HTTP response or an asynchronous HTTP POST request to the originating server.
  5. The EDI exchange audit trail is logged in Amazon CloudWatch Logs.
  6. The EDI document is available for TVS SCS consumption, and a Lambda function processes the document using business logic.

TVS SCS to end customer communication workflow

The following diagram depicts the workflow from TVS SCS to the end customer.

TVS SCS to end customer communication workflow

This workflow demonstrates how TVS SCS uses AWS services to provide timely and accurate updates to customers throughout the delivery process:

  1. The customer confirms the price quote. TVS SCS uploads EDI documents to S3 bucket.
  2. TVS SCS sends a series of updates using the AS2 outbound connector, such as truck allocation, truck departure, truck in-transit status, truck delay notifications, delivery confirmation, and billing invoice. A Lambda function reads the EDI documents from Amazon S3 and runs business logic to generate responses for the end customer.
  3. The EDI documents are sent as an outbound HTTP payload.
  4. The customer AS2 server sends an acknowledgment using MDN.
  5. The EDI exchange audit trail is logged in CloudWatch Logs.
  6. The EDI document is available for the customer’s consumption and further processing.

Results

The following customer challenges were addressed with this solution:

  • It meets end customer requirements for EDI file exchange through AS2 protocol
  • It eliminates the need for in-house AS2 infrastructure management
  • It provides flexibility to add new customers to the file transfer platform

By addressing these challenges and using AWS services, TVS SCS has created a future-proof file transfer platform.

Summary

This post demonstrated how cloud-based services can transform traditional B2B communication processes, offering supply chain companies a path to improved efficiency, compliance, and customer satisfaction. For supply chain providers facing similar challenges, this solution offers a blueprint for modernizing file transfer systems while maintaining compliance with industry standards.

To learn more about this AWS solution for supply chain companies, contact AWS for further assistance. AWS can provide detailed information about implementation, pricing, and how to tailor the solution to your specific business needs. They have teams of experts who can guide companies through the process of modernizing their B2B communication systems using cloud-based services.


About the Authors

Batch data ingestion into Amazon OpenSearch Service using AWS Glue

Post Syndicated from Ravikiran Rao original https://aws.amazon.com/blogs/big-data/batch-data-ingestion-into-amazon-opensearch-service-using-aws-glue/

Organizations constantly work to process and analyze vast volumes of data to derive actionable insights. Effective data ingestion and search capabilities have become essential for use cases like log analytics, application search, and enterprise search. These use cases demand a robust pipeline that can handle high data volumes and enable efficient data exploration.

Apache Spark, an open source powerhouse for large-scale data processing, is widely recognized for its speed, scalability, and ease of use. Its ability to process and transform massive datasets has made it an indispensable tool in modern data engineering. Amazon OpenSearch Service—a community-driven search and analytics solution—empowers organizations to search, aggregate, visualize, and analyze data seamlessly. Together, Spark and OpenSearch Service offer a compelling solution for building powerful data pipelines. However, ingesting data from Spark into OpenSearch Service can present challenges, especially with diverse data sources.

This post showcases how to use Spark on AWS Glue to seamlessly ingest data into OpenSearch Service. We cover batch ingestion methods, share practical examples, and discuss best practices to help you build optimized and scalable data pipelines on AWS.

Overview of solution

AWS Glue is a serverless data integration service that simplifies data preparation and integration tasks for analytics, machine learning, and application development. In this post, we focus on batch data ingestion into OpenSearch Service using Spark on AWS Glue.

AWS Glue offers multiple integration options with OpenSearch Service using various open source and AWS managed libraries, including:

In the following sections, we explore each integration method in detail, guiding you through the setup and implementation. As we progress, we incrementally build the architecture diagram shown in the following figure, providing a clear path for creating robust data pipelines on AWS. Each implementation is independent of the others. We chose to showcase them separately, because in a real-world scenario, only one of the three integration methods is likely to be used.

Image showing the high level architecture diagram

You can find the code base in the accompanying GitHub repo. In the following sections, we walk through the steps to implement the solution.

Prerequisites

Before you deploy this solution, make sure the following prerequisites are in place:

Clone the repository to your local machine

Clone the repository to your local machine and set the BLOG_DIR environment variable. All the relative paths assume BLOG_DIR is set to the repository location in your machine. If BLOG_DIR is not being used, adjust the path accordingly.

git clone [email protected]:aws-samples/opensearch-glue-integration-patterns.git
cd opensearch-glue-integration-patterns
export BLOG_DIR=$(pwd)

Deploy the AWS CloudFormation template to create the necessary infrastructure

The main focus of this post is to demonstrate how to use the mentioned libraries in Spark on AWS Glue to ingest data into OpenSearch Service. Though we center on this core topic, several key AWS components will need to be pre-provisioned for the integration examples, such as a Amazon Virtual Private Cloud (Amazon VPC), multiple Subnets, an AWS Key Management Service (AWS KMS) key, an Amazon Simple Storage Service (Amazon S3) bucket, an AWS Glue role, and an OpenSearch Service cluster with domains for OpenSearch Service and Elasticsearch. To simplify the setup, we’ve automated the provisioning of this core infrastructure using the cloudformation/opensearch-glue-infrastructure.yaml AWS CloudFormation template.

  1. Run the following commands

The CloudFormation template will deploy the necessary networking components (such as VPC and subnets), Amazon CloudWatch logging, AWS Glue role, and OpenSearch Service and Elasticsearch domains required to implement the proposed architecture. Use a strong password (8–128 characters, three of which are lowercase, uppercase, numbers, or special characters, and no /, “, or spaces) and adhere to your organization’s security standards for ESMasterUserPassword and OSMasterUserPassword in the following command:

cd ${BLOG_DIR}/cloudformation/
aws cloudformation deploy \
--template-file ${BLOG_DIR}/cloudformation/opensearch-glue-infrastructure.yaml \
--stack-name GlueOpenSearchStack \
--capabilities CAPABILITY_NAMED_IAM \
--region <AWS_REGION> \
--parameter-overrides \
ESMasterUserPassword=<ES_MASTER_USER_PASSWORD> \
OSMasterUserPassword=<OS_MASTER_USER_PASSWORD>

You should see a success message such as "Successfully created/updated stack – GlueOpenSearchStack" after the resources have been provisioned successfully. Provisioning this CloudFormation stack typically takes approximately 30 minutes to complete.

  1. On the AWS CloudFormation console, locate the GlueOpenSearchStack stack, and confirm that its status is CREATE_COMPLETE.

Image showing the "CREATE_COMPLETE" status of cloudformation template

You can review the deployed resources on the Resources tab, as shown in the following screenshot.The screenshot does not display all the created resources.

Image showing the "Resources" tab of cloudformation template

Additional setup steps

In this section, we collect essential information, including the S3 bucket name and the OpenSearch Service and Elasticsearch domain endpoints. These details are required for executing the code in subsequent sections.

Capture the details of the provisioned resources

Use the following AWS CLI command to extract and save the output values from the CloudFormation stack to a file named GlueOpenSearchStack_outputs.txt. We refer to the values in this file in upcoming steps.

aws cloudformation describe-stacks \
--stack-name GlueOpenSearchStack \
--query 'sort_by(Stacks[0].Outputs[], &OutputKey)[].{Key:OutputKey,Value:OutputValue}' \
--output table \
--no-cli-pager \
--region <AWS_REGION> > ${BLOG_DIR}/GlueOpenSearchStack_outputs.txt

Download NY Green Taxi December 2022 dataset and copy to S3 bucket

The purpose of this post is to demonstrate the technical implementation of ingesting data into OpenSearch Service using AWS Glue. Understanding the dataset itself is not essential, aside from its data format, which we discuss in AWS Glue notebooks in later sections. To learn more about the dataset, you can find additional information on the NYC Taxi and Limousine Commission website.

We specifically request that you download the December 2022 dataset, because we have tested the solution using this particular dataset:

S3_BUCKET_NAME=$(awk -F '|' '$2 ~ /S3Bucket/ {gsub(/^[ \t]+|[ \t]+$/, "", $3); print $3}' ${BLOG_DIR}/GlueOpenSearchStack_outputs.txt)
mkdir -p ${BLOG_DIR}/datasets && cd ${BLOG_DIR}/datasets
curl -O https://d37ci6vzurychx.cloudfront.net/trip-data/green_tripdata_2022-12.parquet
aws s3 cp green_tripdata_2022-12.parquet s3://${S3_BUCKET_NAME}/datasets/green_tripdata_2022-12.parquet

Download the required JARs from the Maven repository and copy to S3 bucket

We’ve specified a particular JAR file version to ensure stable deployment experience. However, we recommend adhering to your organization’s security best practices and reviewing any known vulnerabilities in the version of the JAR files before deployment. AWS does not guarantee the security of any open-source code used here. Additionally, please verify the downloaded JAR file’s checksum against the published value to confirm its integrity and authenticity.

mkdir -p ${BLOG_DIR}/jars && cd ${BLOG_DIR}/jars
# OpenSearch Service jar
curl -O https://repo1.maven.org/maven2/org/opensearch/client/opensearch-spark-30_2.12/1.0.1/opensearch-spark-30_2.12-1.0.1.jar
aws s3 cp opensearch-spark-30_2.12-1.0.1.jar s3://${S3_BUCKET_NAME}/jars/opensearch-spark-30_2.12-1.0.1.jar
# Elasticsearch jar
curl -O https://repo1.maven.org/maven2/org/elasticsearch/elasticsearch-spark-30_2.12/7.17.23/elasticsearch-spark-30_2.12-7.17.23.jar
aws s3 cp elasticsearch-spark-30_2.12-7.17.23.jar s3://${S3_BUCKET_NAME}/jars/elasticsearch-spark-30_2.12-7.17.23.jar

In the following sections, we implement the individual data ingestion methods as outlined in the architecture diagram.

Ingest data into OpenSearch Service using the OpenSearch Spark library

In this section, we load an OpenSearch Service index using Spark and the OpenSearch Spark library. We demonstrate this implementation by using AWS Glue notebooks, employing basic authentication using user name and password.

To demonstrate the ingestion mechanisms, we have provided the Spark-and-OpenSearch-Code-Steps.ipynb notebook with detailed instructions. Follow the steps in this section in conjunction with the instructions in the notebook.

Set up the AWS Glue Studio notebook

Complete the following steps:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Under Create job, choose Notebook.

Image showing AWS console page for AWS Glue to open notebook

  1. Upload the notebook file located at ${BLOG_DIR}/glue_jobs/Spark-and-OpenSearch-Code-Steps.ipynb.
  2. For IAM role, choose the AWS Glue job IAM role that begins with GlueOpenSearchStack-GlueRole-*.

Image showing AWS console page for AWS Glue to open notebook

  1. Enter a name for the notebook (for example, Spark-and-OpenSearch-Code-Steps) and choose Save.

Image showing AWS Glue OpenSearch Notebook

Replace the placeholder values in the notebook

Complete the following steps to update the placeholders in the notebook:

  1. In Step 1 in the notebook, replace the placeholder <GLUE-INTERACTIVE-SESSION-CONNECTION-NAME> with the AWS Glue interactive session connection name. You can get the name of the interactive session by executing the following command:
cd ${BLOG_DIR}
awk -F '|' '$2 ~ /GlueInteractiveSessionConnectionName/ {gsub(/^[ \t]+|[ \t]+$/, "", $3); print $3}' ${BLOG_DIR}/GlueOpenSearchStack_outputs.txt
  1. In Step 1 in the notebook, replace the placeholder <S3-BUCKET-NAME> and populate the variable s3_bucket with the bucket name. You can get the name of the S3 bucket by executing the following command:
awk -F '|' '$2 ~ /S3Bucket/ {gsub(/^[ \t]+|[ \t]+$/, "", $3); print $3}' ${BLOG_DIR}/GlueOpenSearchStack_outputs.txt
  1. In Step 4 in the notebook, replace <OPEN-SEARCH-DOMAIN-WITHOUT-HTTPS> with the OpenSearch Service domain name. You can get the domain name by executing the following command:
awk -F '|' '$2 ~ /OpenSearchDomainEndpoint/ {gsub(/^[ \t]+|[ \t]+$/, "", $3); print $3}' ${BLOG_DIR}/GlueOpenSearchStack_outputs.txt

Run the notebook

Run each cell of the notebook to load data into the OpenSearch Service domain and read it back to verify the successful load. Refer to the detailed instructions within the notebook for execution-specific guidance.

Spark write modes (append vs. overwrite)

It is recommended to write data incrementally into OpenSearch Service indexes using the append mode, as demonstrated in Step 8 in the notebook. However, in certain cases, you may need to refresh the entire dataset in the OpenSearch Service index. In these scenarios, you can use the overwrite mode, though it is not advised for large indexes. When using overwrite mode, the Spark library deletes rows from the OpenSearch Service index one by one and then rewrites the data, which can be inefficient for large datasets. To avoid this, you can implement a preprocessing step in Spark to identify insertions and updates, and then write the data into OpenSearch Service using append mode.

Ingest data into Elasticsearch using the Elasticsearch Hadoop library

In this section, we load an Elasticsearch index using Spark and the Elasticsearch Hadoop Library. We demonstrate this implementation by using AWS Glue as the engine for Spark.

Set up the AWS Glue Studio notebook

Complete the following steps to set up the notebook:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Under Create job, choose Notebook.

Image showing AWS console page for AWS Glue to open notebook

  1. Upload the notebook file located at ${BLOG_DIR}/glue_jobs/Spark-and-Elasticsearch-Code-Steps.ipynb.
  2. For IAM role, choose the AWS Glue job IAM role that begins with GlueOpenSearchStack-GlueRole-*.

Image showing AWS console page for AWS Glue to open notebook

  1. Enter a name for the notebook (for example, Spark-and-ElasticSearch-Code-Steps) and choose Save.

Image showing AWS Glue Elasticsearch Notebook

Replace the placeholder values in the notebook

Complete the following steps:

  1. In Step 1 in the notebook, replace the placeholder <GLUE-INTERACTIVE-SESSION-CONNECTION-NAME> with the AWS Glue interactive session connection name. You can get the name of the interactive session by executing the following command:
awk -F '|' '$2 ~ /GlueInteractiveSessionConnectionName/ {gsub(/^[ \t]+|[ \t]+$/, "", $3); print $3}' ${BLOG_DIR}/GlueOpenSearchStack_outputs.txt
  1. In Step 1 in the notebook, replace the placeholder <S3-BUCKET-NAME> and populate the variable s3_bucket with the bucket name. You can get the name of the S3 bucket by executing the following command:
awk -F '|' '$2 ~ /S3Bucket/ {gsub(/^[ \t]+|[ \t]+$/, "", $3); print $3}' ${BLOG_DIR}/GlueOpenSearchStack_outputs.txt
  1. In Step 4 in the notebook, replace <ELASTIC-SEARCH-DOMAIN-WITHOUT-HTTPS> with the Elasticsearch domain name. You can get the domain name by executing the following command:
awk -F '|' '$2 ~ /ElasticsearchDomainEndpoint/ {gsub(/^[ \t]+|[ \t]+$/, "", $3); print $3}' ${BLOG_DIR}/GlueOpenSearchStack_outputs.txt

Run the notebook

Run each cell in the notebook to load data to the Elasticsearch domain and read it back to verify the successful load. Refer to the detailed instructions within the notebook for execution-specific guidance.

Ingest data into OpenSearch Service using the AWS Glue OpenSearch Service connection

In this section, we load an OpenSearch Service index using Spark and the AWS Glue OpenSearch Service connection.

Create the AWS Glue job

Complete the following steps to create an AWS Glue Visual ETL job:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Under Create job, choose Visual ETL

This will open the AWS Glue job visual editor.Image showing AWS console page for AWS Glue to open Visual ETL

  1. Choose the plus sign, and under Sources, choose Amazon S3.

Image showing AWS console page for AWS Glue Visual Editor

  1. In the visual editor, choose the Data Source – S3 bucket node.
  2. In the Data source properties – S3 pane, configure the data source as follows:
    • For S3 source type, select S3 location.
    • For S3 URL, choose Browse S3, and choose the green_tripdata_2022-12.parquet file from the designated S3 bucket.
    • For Data format, choose Parquet.
  1. Choose Infer schema to let AWS Glue detect the schema of the data.

This will set up your data source from the specified S3 bucket.

Image showing AWS console page for AWS Glue Visual Editor

  1. Choose the plus sign again to add a new node.
  2. For Transforms, choose Drop Fields to include this transformation step.

This will allow you to remove any unnecessary fields from your dataset before loading it into OpenSearch Service.

Image showing AWS console page for AWS Glue Visual Editor

  1. Choose the Drop Fields transform node, then select the following fields to drop from the dataset:
    • payment_type
    • trip_type
    • congestion_surcharge

This will remove these fields from the data before it is loaded into OpenSearch Service.

Image showing AWS console page for AWS Glue Visual Editor

  1. Choose the plus sign again to add a new node.
  2. For Targets, choose Amazon OpenSearch Service.

This will configure OpenSearch Service as the destination for the data being processed.

Image showing AWS console page for AWS Glue Visual Editor

  1. Choose the Data target – Amazon OpenSearch Service node and configure it as follows:
    • For Amazon OpenSearch Service connection, choose the connection GlueOpenSearchServiceConnec-* from the drop down.
    • For Index, enter green_taxi. The green_taxi index was created earlier in the “Ingest data into OpenSearch Service using the OpenSearch Spark library” section.

This configures the OpenSearch Service to write the processed data to the specified index.

Image showing AWS console page for AWS Glue Visual Editor

  1. On the Job details tab, update the job details as follows:
    • For Name, enter a name (for example, Spark-and-Glue-OpenSearch-Connection).
    • For Description, enter an optional description (for example, AWS Glue job using Glue OpenSearch Connection to load data into Amazon OpenSearch Service).
    • For IAM role, choose the role starting with GlueOpenSearchStack-GlueRole-*.
    • For the Glue version, choose Glue 4.0 – Supports spark 3.3, Scala 2, Python 3
    • Leave the rest of the fields as default.
    • Choose Save to save the changes.

Image showing AWS console page for AWS Glue Visual Editor

  1. To run the AWS Glue job Spark-and-Glue-OpenSearch-Connector, choose Run.

This will initiate the job execution.

Image showing AWS console page for AWS Glue Visual Editor

  1. Choose the Runs tab and wait for the AWS Glue job to complete successfully.

You will see the status change to Succeeded when the job is complete.

Image showing AWS console page for AWS Glue job run status

Clean up

To clean up your resources, complete the following steps:

  1. Delete the CloudFormation stack:
aws cloudformation delete-stack \
--stack-name GlueOpenSearchStack \
--region <AWS_REGION>
  1. Delete the AWS Glue jobs:
    • On the AWS Glue console, under ETL jobs in the navigation pane, choose Visual ETL.
    • Select the jobs you created (Spark-and-Glue-OpenSearch-Connector, Spark-and-ElasticSearch-Code-Steps, and Spark-and-OpenSearch-Code-Steps) and on the Actions menu, choose Delete.

Conclusion

In this post, we explored several ways to ingest data into OpenSearch Service using Spark on AWS Glue. We demonstrated the use of three key libraries: the AWS Glue OpenSearch Service connection, the OpenSearch Spark Library, and the Elasticsearch Hadoop Library. The methods outlined in this post can help you streamline your data ingestion into OpenSearch Service.

If you’re interested in learning more and getting hands-on experience, we’ve created a workshop that walks you through the entire process in detail. You can explore the full setup for ingesting data into OpenSearch Service, handling both batch and real-time streams, and building dashboards. Check out the workshop Unified Real-Time Data Processing and Analytics Using Amazon OpenSearch and Apache Spark to deepen your understanding and apply these techniques step by step.


About the Authors

Ravikiran Rao is a Data Architect at Amazon Web Services and is passionate about solving complex data challenges for various customers. Outside of work, he is a theater enthusiast and amateur tennis player.

Vishwa Gupta is a Senior Data Architect with the AWS Professional Services Analytics Practice. He helps customers implement big data and analytics solutions. Outside of work, he enjoys spending time with family, traveling, and trying new food.

Suvojit Dasgupta is a Principal Data Architect at Amazon Web Services. He leads a team of skilled engineers in designing and building scalable data solutions for AWS customers. He specializes in developing and implementing innovative data architectures to address complex business challenges.This post showcases how to use Spark on AWS Glue to seamlessly ingest data into OpenSearch Service. We cover batch ingestion methods, share practical examples, and discuss best practices to help you build optimized and scalable data pipelines on AWS.

Efficient satellite imagery supply with AWS Serverless at BASF Digital Farming GmbH

Post Syndicated from Kevin S. Ridolfi original https://aws.amazon.com/blogs/architecture/efficient-satellite-imagery-supply-with-aws-serverless-at-basf-digital-farming-gmbh/

This post was co-written with Dr. Jan Melchior at BASF Digital Farming GmbH and xarvio Digital Farming Solutions.

BASF Digital Farming’s mission is to support farmers worldwide with cutting-edge digital agronomic decision advice by using its main crop optimization platform, xarvio FIELD MANAGER. This necessitates providing the most recent satellite imagery available as quickly as possible. This blog post describes the serverless architecture developed by BASF Digital Farming for efficiently downloading and supplying satellite imagery from various providers to support its xarvio platform.

Screenshot showing the xarvio Field Manager platform

Figure 1. Screenshot showing the xarvio Field Manager platform

Architecture

Figure 2 shows the serverless architecture implemented with AWS services for downloading and processing satellite imagery. The subscription management components handle subscription creation, updates, and deletions, while the actual data downloading and processing occurs in AWS Step Functions.

Serverless implementation of the new imagery service

Figure 2. Serverless implementation of the new imagery service

  1. Subscriptions are created using Amazon API Gateway for external API access, which provides request throttling and can be used to manage API request authorizations.
  2. An AWS Lambda API function manages subscriptions. It implements common create, read, update, and delete operations with request validations and provides an endpoint for replaying failed requests. Subscriptions contain geometry, data provider, as well as start and end date and other parameters, which are stored in the subscription database (Step 7) before a message is sent out for processing.
    Notice that the entire architecture is serverless and thus allows for theoretically unbounded scaling. In case of a bug, this can lead to severe cost impacts, so we implemented a safety buffer, which enables us to prioritize and limit the number of Step Functions executions of the processing pipeline.
  3. All requests (such as the initial request for imagery when a subscription is created) are sent to the Amazon Simple Queue Service (Amazon SQS) processing queue first, which functions as a processing buffer and allows for request prioritization.
  4. Subsequently, Amazon EventBridge Pipes connects the processing buffer with AWS Step Functions. It handles pipe-internal errors automatically; for example, when the Step Functions concurrency limit is reached, the invocation will be retired automatically. This does not handle exceptions raised within Step Functions, such as runtime errors.
  5. AWS Step Functions then performs the actual downloading, processing, and ingestion to the STAC catalog of satellite data from different providers. In case of failure, the request message with error description is sent to the failure queue.
  6. Step Functions uploads the data to Amazon Simple Storage Service (Amazon S3), which stores satellite imagery data.
  7. Following this, Step Functions updates the subscriptions in the Amazon DynamoDB-based subscription database, which stores relevant metadata, such as start and end date, boundary, provider, collection, and last update.
  8. A notification is sent out to inform the user that new data is available through Amazon Simple Notification Service (Amazon SNS), which informs users and services about any updates on a subscription, such as new data being available or subscriptions having been created, deleted, updated, or having failed.
  9. Next, the data is published to our internal STAC catalog, which registers the satellite imagery and makes it directly accessible for subsequent processing.
  10. In case of failed Step Functions execution in Step 5, the Amazon SQS-based failure queue buffers failed executions. Failure messages contain the error message and request body. Depending on error reasons, they can be replayed using the corresponding API endpoint, enabling reprocessing through the replay endpoint on the API Lambda function. The endpoint also allows users to filter messages based on their failure type and to delete messages that cannot be replayed.
  11. An update checker, built on AWS Lambda, regularly checks whether a subscription can be updated. It is triggered in conjunction with an event scheduler every 5 minutes, checks the database for subscriptions that can be updated, and sends update request messages to the processing buffer. Besides actively checking resources, such as API endpoints and STAC catalogs, it also sends out an update message if a notification was received, for example, through an external notification service.
  12. Finally, a delete checker, also built on AWS Lambda, identifies subscriptions that can be deleted. It is triggered in conjunction with an event scheduler every 12 hours. It regularly checks the database for subscriptions that can be deleted and removes them from the database, the S3 bucket, and the STAC catalog. As a safety mechanism, a subscription will first be marked for deletion for 6 months before it gets deleted.

Imagery step function

The actual downloading and processing of data from different providers is handled by the imagery function, illustrated for two different providers (Public and Planet) in Figure 3.

Diagram showing detail state machine for the Imagery Step Function

Figure 3. Diagram showing detail state machine for the Imagery Step Function

  1. When a request arrives, the provider choice state determines the provider from the request body, depending on which the Step Functions flow routes to different Lambda states.
  2. In case a public provider is selected (for example, Earth Search), the Public_Provider Lambda function downloads the data from STAC-based open data providers and directly uploads it to the S3 data bucket, as shown in Figure 2.
  3. In case Planet data is selected, the data retrieval involves an asynchronous call to an external API: First, the Planet_Requester sends an order to the Planet API, together with a task token for pausing Step Functions and the URL of the Planet_Webhook Lambda function.
  4. The Planet_Webhook function is invoked by Planet when the requested order is available for downloading. Given the transmitted task token, Step Functions is resumed with the next state.
  5. Subsequently, the Planet_Provider Lambda function downloads and processes the Planet data.
  6. For both public providers and Planet, the subsequent Public_Provider Lambda function updates the subscription database entries, as shown in Figure 2 (for example, with the latest available timestamp), and adds the download and processed data to the internal STAC catalog, before it ends in the Success state.
  7. If an error occurs in any of the Lambda functions (2, 3, 5, 6), an error message is prepared in the Error_Parsing If an unknown provider is handed in, an error message, including the request body, is prepared in the Error_Provider_Unknown state. In both cases, the error message is pushed to the Failure_Queue (refer to #10 of Figure 2), before it ends in the Failure state.

Conclusion

BASF Digital Farming GmbH developed a serverless architecture on AWS for efficiently downloading and supplying satellite imagery for use by its xarvio platform. This architecture led to a 5x faster delivery rate, an 80% cost reduction through on-demand data downloading, and a 3x accelerated development cycle. Future work will include optimizing the architecture, exploring additional AWS services, and onboarding more satellite imagery providers. Similar serverless architectures using AWS services like AWS Step Functions, AWS Lambda, and Amazon API Gateway can enhance flexibility, scalability, and cost efficiency in imagery provisioning. Learn more about AWS serverless offerings at aws.amazon.com/serverless.

How ANZ Institutional Division built a federated data platform to enable their domain teams to build data products to support business outcomes

Post Syndicated from Leo Ramsamy original https://aws.amazon.com/blogs/big-data/how-anz-institutional-division-built-a-federated-data-platform-to-enable-their-domain-teams-to-build-data-products-to-support-business-outcomes/

In today’s rapidly evolving financial landscape, data is the bedrock of innovation, enhancing customer and employee experiences and securing a competitive edge. Recognizing this paradigm shift, ANZ Institutional Division has embarked on a transformative journey to redefine its approach to data management, utilization, and extracting significant business value from data insights.

Like many large financial institutions, ANZ Institutional Division operated with siloed data practices and centralized data management teams. As time went on, the limitations of this approach became apparent due to rising data complexity, larger volumes, and the growing demand for swift, business-driven insights. Consequently, the bank encountered several challenges and needed to take the following actions:

  • Create business insights from untapped data potential, estimated to be approximately $150 million in the Institutional Division alone
  • Improve operational efficiency by removing manual data handling, the use of spreadsheets, and duplicate data entries
  • Increase agility by making data expertise more readily available, thereby improving time to market and overall customer experience
  • Address data quality
  • Standardize tooling and remove the Shadow IT culture, driving scalability, reducing risk, and minimizing overall operational inefficiencies

These challenges are not unique to ANZ Institutional Division. Globally, financial institutions have been experiencing similar issues, prompting a widespread reassessment of traditional data management approaches.

One major trend, embraced by many financial institutions, has been the adoption of the data mesh architecture and the shift towards treating data as a product. This paradigm, pioneered by thought leaders like Zhamak Dehghani, introduces a decentralized approach to data management that aligns closely with modern organizational structures and agile methodologies.

Some notable global examples of leading companies embracing and implementing this trend are JPMorgan Chase, Capital One, and Saxo Bank.

Inspired by these global trends and driven by its own unique challenges, ANZ’s Institutional Division decided to pivot from viewing data as a byproduct of projects to treating it as a valuable product in its own right.

This shift promises several business benefits:

  • Empowered domain expertise – By decentralizing data ownership to domain-based teams, ANZ can use the deep business knowledge within each unit to create more relevant and valuable data products
  • Increased agility – Domain teams can now respond more quickly to business needs, creating and iterating on data products without relying on a centralized bottleneck
  • Improved data quality – With domain experts overseeing their own data, there’s a greater likelihood of catching and correcting quality issues at the source
  • Scalability – The federated approach allows for greater scalability, enabling ANZ to handle increasing data volumes and complexity more effectively
  • Innovation catalyst – By democratizing data access and empowering teams to create data products, ANZ is fostering a culture of innovation and data-driven decision-making across the organization

This transition is not just about technology; it represents a fundamental shift in how ANZ views and values its data assets. By treating data as a product, the bank is positioned to not only overcome current challenges, but to unlock new opportunities for growth, customer service, and competitive advantage.

This post explores how the shift to a data product mindset is being implemented, the challenges faced, and the early wins that are shaping the future of data management in the Institutional Division.

ANZ’s federated data strategy

In response to the challenges, ANZ Group formulated a data strategy that focuses on empowering employees to securely use data to improve the sustainability and financial well-being of their customers. At its core are the following pillars:

  • Introducing new ways of working that focus on generating customer value first
  • New technology platforms and tooling that allow the bank to collect, share, archive, and dispose data in a secure and controlled way
  • Achieving consistency in how data is produced and consumed across the entire bank through data products and better-connected systems
  • Supporting the bank’s risk and regulatory obligations by providing a secure and resilient data platform that provides fine-grained, controlled access to quality data products

ANZ has made the strategic decision to adopt an architectural and operational model aligned with the data mesh paradigm, which revolves around four key principles: domain ownership, data as a product, a self-serve data platform, and federated computational governance.

Domain ownership recognizes that the teams generating the data have the deepest understanding of it and are therefore best suited to manage, govern, and share it effectively. This principle makes sure data accountability remains close to the source, fostering higher data quality and relevance.

Treating data as a product instils a product-centric mindset, emphasizing that data must be secure, discoverable, understandable, interoperable, reusable, and managed throughout its lifecycle. This principle makes sure data consumers, both internal and external, derive consistent value from well-designed data products.

A self-serve data platform empowers domains to create, discover, and consume data products independently. It abstracts technical complexities and provides user-friendly tools, enabling a scalable, repeatable, and automated approach to producing high-quality data products.

Under the federated mesh architecture, each divisional mesh functions as a node within the broader enterprise data mesh, maintaining a degree of autonomy in managing its data products. To effectively coordinate these autonomous nodes and facilitate seamless integration, enterprise-wide standards, such as those related to data governance, interoperability, and security, are essential to maintain alignment and consistency across all nodes and domains and teams within.

With this approach, each node in ANZ maintains its divisional alignment and adherence to data risk and governance standards and policies to manage local data products and data assets. This enables global discoverability and collaboration without centralizing ownership or operations.

As a result, governance resides with the data products themselves, making sure standards and policies, such as access control, data quality, and compliance, are enforced where the data lives. In this regard, the enterprise data product catalog acts as a federated portal, facilitating cross-domain access and interoperability while maintaining alignment with governance principles. This model balances node or domain-level autonomy with enterprise-level oversight, creating a scalable and consistent framework across ANZ.

Within the ANZ enterprise data mesh strategy, aligning data mesh nodes with the ANZ Group’s divisional structure provides optimal alignment between data mesh principles and organizational structure, as shown in the following diagram.

Central to the success of this strategy is its support for each division’s autonomy and freedom to choose their own domain structure, which is closely aligned to their business needs. Divisions decide how many domains to have within their node; some may have one, others many. These nodes can implement analytical platforms like data lake houses, data warehouses, or data marts, all united by producing data products. Nodes and domains serve business needs and are not technology mandated.

Under the federated computational governance model, the ANZ Group strategy defines guardrails that treat a node as a logical data container suitable for the following:

  • Ingestion and metadata management
  • Creating source-aligned data products complying with ANZ’s Data Product Specification (DPS)
  • Integrating source-aligned data products from other nodes
  • Producing consumer-aligned data products for specific business purposes
  • Publishing conforming data products to ANZ’s Data Product Catalog (DPC)

Following on from this strategy is organizing its domain structure to provide autonomy to various functional teams while preserving the core values of data mesh. The following diagram depicts an example of the possible structure.

For instance, Domain A will have the flexibility to create data products that can be published to the divisional catalog, while also maintaining the autonomy to develop data products that are exclusively accessible to teams within the domain. These products will not be available to others until they are deemed ready for broader enterprise use.

This strategy supports each division’s autonomy to implement their own data catalogs and decide which data products to publish to the group-level catalog. This flexibility extends to divisional domains, which can choose which data products to publish to the divisional catalog or keep visible only to domain consumers.

Institutional Data & AI Platform architecture

The Institutional Division has implemented a self-service data platform to enable the domain teams to build and manage data products autonomously. The Institutional Data & AI platform adopts a federated approach to data while centralizing the metadata to facilitate simpler discovery and sharing of data products. The following diagram illustrates the building blocks of the Institutional Data & AI Platform.

The building blocks are as follows:

  1. Foundational Data & AI Platform capabilities – A dedicated data platform team provides domain-agnostic tools, systems, and capabilities to enable autonomous data product development across domains. This self-serve infrastructure allows domain teams to manage the full data lifecycle without relying on a centralized data team. Key capabilities include data storage, data onboarding and transformation, and data utilities that facilitate data sharing with interoperability between domains. These capabilities abstract the technical complexities associated with data management infrastructure, allowing domain experts to focus on creating valuable data products rather than infrastructure management.
  2. Domain-owned data assets – The domain-oriented data ownership approach distributes responsibility for data across the business units within the Institutional Division. Domain teams are responsible for developing, deploying, and managing their own analytical data products alongside operational data services. Data contracts authored by data product owners automate data product creation and provide a standard to access data products. By treating the data as a product, the outcome is a reusable asset that outlives a project and meets the needs of the enterprise consumer. Consumer feedback and demand drives creation and maintenance of the data product.
  3. Division-level metadata management and data governance – A centrally hosted service provides domain teams with the capability to publish their data products along with relevant metadata, like business definitions and lineage. Some of the key features implemented are:
    1. Metadata management that centralizes metadata and presents it within the context of data products, such as data quality scores and data product lineage.
    2. A data portal for consumers to discover data products and access associated metadata.
    3. Subscription workflows that simplify access management to the data products.
    4. Computational governance that enforces divisional and enterprise data policies and standards, such as data classification and business data models for aligning terminology.

The following diagram is a high-level example of the technical architecture approach towards the Institutional Data & AI Platform. The solution uses a building block approach, on a cloud-centered platform comprised of AWS services, with partner solutions and open standards like OpenLineage and Apache Iceberg.

Let’s look at the key services that enable the federated platform to operate at scale:

  • Data storage and processing:
    • Apache Iceberg on Amazon Simple Storage Service (Amazon S3) offers an optimized way to store data assets and products and promotes interoperability across other services
    • Amazon Redshift allows domain teams to create and manage fit-for-purpose data marts
    • AWS Lambda and AWS Glue are used for data onboarding and processing, and data utilities created in Python and PySpark promote reusability and quality across the data processing pipelines
    • dbt simplifies data transformation rules and allows sub-domain data analysts to build modeling logic as SQL statements
    • Amazon Managed Workflows for Apache Airflow (Amazon MWAA) enables efficient management of workflows and data pipeline orchestration using out-of-the-box integrations with AWS services
  • Metadata management and data governance:
    • To maintain data reliability and accuracy, a robust data quality framework using Soda core is used that automates data quality using checks defined in a data contract
    • Amazon DataZone enables data product cataloging, discovery, metadata management, and implementing computational governance
    • OpenLineage simplifies harvesting and collection of data and process-level lineage, which are then published to Amazon DataZone
    • AWS Lake Formation, combined with AWS Glue Data Catalog, provides data governance and access management to data products that reside within sub-domains
  • Analytics:
    • Tableau offers capabilities for sub-domains with data visualization and business intelligence capabilities
  • Observability and security:
    • Observability needs of the platform are built into all the processes using monitoring, with logging functionality provided by Amazon CloudWatch and AWS CloudTrail
    • AWS Secrets Manager makes sure secrets are stored and made available for data pipelines to access services in a secure manner

The technical implementation actualizes the data product strategy at ANZ Institutional Division. Amazon DataZone plays an essential role in facilitating data product management for the domain teams. The service addresses several critical aspects of the Institutional Division’s data product strategy, including:

  • Data cataloging and metadata management – Amazon DataZone provides comprehensive data cataloging and metadata management capabilities
  • Data governance and compliance – Effective data governance is essential for scaling data products
  • Self-service capabilities – Amazon DataZone empowers domain teams with self-service capabilities, enabling them to create, manage, and deploy data products independently
  • Integration and interoperability – One of the challenges in scaling data products is providing seamless integration across various data sources and systems
  • Collaboration and sharing – Amazon DataZone provides a platform for sharing data and metadata across teams and domains

Institutional Division’s delivery model to achieve scale

The Institutional Division has successfully used the federated architecture, and key to this delivery model is the implementation of Foundational Data & AI Platform capabilities that serve all domains within the division. This model promotes self-service and accelerates the delivery of subsequent initiatives by using the capabilities built for previous use cases.

To evaluate the success of the delivery model, ANZ has implemented key metrics, such as cost transparency and domain adoption, to guide the data mesh governance team in refining the delivery approach. For instance, one enhancement involves integrating cross-functional squads to support data literacy.

The key to scaling the Institutional Division operating model are the following considerations:

  • Data as a product approach – Use techniques like event storming and domain-driven design to capture business events and their meanings.
  • Education and enablement – Conduct learning interventions to upskill teams on understanding and using the data as a product approach.
  • Iterative data platform delivery – Work backward from business initiative to iteratively deliver self-service data platform infrastructure capabilities.
  • Managing demand efficiently – Implement a feedback mechanism to manage demand on data products. Track and manage data debt using standard data contract specifications. Most importantly, adopt governance and standards to make sure data products are built and maintained with a long-term perspective, minimizing technical debt.

“The Institutional Data & Analytics Platform (IDAP) has allowed the Institutional team to establish a base foundation to allow various teams to aggregate and consume the wealth of data across the division. This self-service platform enables business leaders to both create and consume reusable data products, unlocking value across this division. It’s also an excellent proof point for our broader data mesh architecture, allowing us to connect this divisional data to broader enterprise data stores—further positioning us to put the customer at the center of everything we do.”

– Tim Hogarth, CTO ANZ

“AWS believes that democratizing data, while not compromising on security and fine-grained access, is a key component of any future-proof, scalable data platform, so we are pleased to be enabling ANZ bank’s IDAP metadata management and data governance capabilities through Amazon DataZone. This allows the diverse business functions at ANZ the autonomy to self-serve on their data needs with built-in governance.”

– Shikha Verma, Head of Product, Amazon DataZone

Conclusion

ANZ’s journey to move towards a data product approach has improved the organization’s approach to manage data and reduce data silos, and has positioned it to become a data-driven, customer-centric organization. By combining federated platform practices and adopting AWS services and open standards, ANZ Institutional Division is achieving its objectives in decentralization with a scalable data platform that enables its domain teams to make informed decisions, drive innovation, and maintain a competitive edge.

Special thanks: This implementation success is a result of close collaboration between ANZ Institutional Division, AWS ProServe, and the AWS account team. We want to thank ANZ Institutional Executives and the Leadership Team for the strong sponsorship and direction.


About the Authors

Leo Ramsamy is a Platform Architect specializing in data and analytics for ANZ’s Institutional division. He focuses on modern data practices, including Data Mesh architecture, data governance, quality management, and observability. His work aligns data strategies with business goals, improving accessibility and enabling better decision-making across ANZ.

Srinivasan Kuppusamy is a Senior Cloud Architect – Data at AWS ProServe, where he helps customers solve their business problems using the power of AWS Cloud technology. His areas of interests are data and analytics, data governance, and AI/ML.

Rada Stanic is a Chief Technologist at Amazon Web Services, where she helps ANZ customers across different segments solve their business problems using AWS Cloud technologies. Her special areas of interest are data analytics, machine learning/AI, and application modernization.

Let’s Architect! Serverless developer experience in AWS

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-serverless-developer-experience-in-aws/

Are you a developer approaching serverless for the first time, or even an experienced one looking for a better way to accelerate your feedback loop from code to production? This collection of resources is perfect for you!

There are plenty of developer goodies available on AWS to streamline your code creation and achieve a faster flow in your development lifecycle. Let us share a few examples with you.

What if I told you that you could have an assistant to create your tests? Or that you could review the schema of DynamoDB tables without logging into the AWS Console? Get ready to discover some game-changing tools and techniques that will revolutionize your serverless development process.

And if you want to know more, check out the AWS developer center for more content dedicated to your developer experience on AWS.

Enjoy the journey!

Introducing an enhanced local IDE experience for AWS Lambda developers

We’re excited to announce significant enhancements to the AWS Toolkit, designed to streamline the AWS Lambda development experience. These new features bring the power of Lambda directly to your local development environment, allowing you to work more efficiently within your preferred IDE.

With this update, you can now create, test, and debug Lambda functions locally with unprecedented ease. The toolkit supports local invocation of Lambda functions, enabling real-time testing and debugging without cloud deployment. We’ve also incorporated intelligent code completion and inline documentation for AWS SDK calls, reducing errors and accelerating your coding process.

These improvements offer substantial benefits: faster iteration cycles, deeper insights into Lambda function behavior, and the ability to deliver high-quality serverless applications more rapidly. Whether you’re new to serverless or an experienced Lambda developer, this enhanced local development experience provides a more intuitive and productive environment for building cloud-native solutions.

AWS Toolkit offers the possibility to retrieve real-time the logs of your AWS Lambda functions directly inside your IDE

Figure 1. AWS Toolkit offers the possibility to retrieve real-time the logs of your AWS Lambda functions directly inside your IDE

Take me to this blog

Test Driven Development with Amazon Q Developer

Amazon Q for developers is a versatile AI-powered assistant designed to enhance various aspects of the software development lifecycle. This innovative tool can help streamline numerous tasks, from writing code and documentation to generating unit tests, effectively reducing the time spent on common development activities. By embracing Amazon Q Developer, developers can boost their productivity and focus more on creative problem-solving, with capabilities like test generation serving as just one example of how it can accelerate the development process and improve code quality.

In this example, you will discover how Amazon Q Developer can help out to embrace test-driven development (TDD) in your projects.

Amazon Q developer in action! As you can see you can choose the right recommendation for your code

Figure 2. Amazon Q Developer in action! As you can see you can choose the right recommendation for your code

Take me to this blog

Stop guesstimating the Lambda functions memory size

Optimizing Lambda function performance is crucial for both cost efficiency and user experience, yet many developers still rely on guesswork when setting memory allocations. This approach often leads to suboptimal configurations, resulting in either wasted resources or underperforming functions. Here is where AWS Lambda Power Tuning comes in. By automatically testing your Lambda function with various memory configurations, you can identify the optimal balance between performance and cost. This data-driven approach ensures your functions run at peak efficiency, potentially reducing costs and improving response times. Moreover, as your application evolves, regular power tuning can help you adapt to changing requirements and usage patterns.

The output of running Lambda Power Tuning with your code is a diagram that shows you the best memory size based on your goals. Either optimized for cost or response time or you can choose a more balanced approach

Figure 3. The output of running Lambda Power Tuning with your code is a diagram that shows you the best memory size based on your goals. Either optimized for cost or response time or you can choose a more balanced approach

Take me to this tool

NoSQL Workbench for Amazon DynamoDB

Developers working with Amazon DynamoDB have a powerful ally in their local development toolkit: NoSQL Workbench for Amazon DynamoDB. This intuitive, graphical tool changes the way you interact with DynamoDB tables, offering a fast and efficient feedback loop right on your laptop. With NoSQL Workbench, you can visually design, create, and modify your DynamoDB table structures without the need to constantly access the AWS Console. The tool’s data modeler allows you to experiment with different schemas, ensuring optimal design before deployment. Need to populate your tables for testing? NoSQL Workbench has you covered with its data visualization and manipulation features, enabling quick data insertion and querying. Moreover, its ability to generate sample data and visualize query results in real-time accelerates the development and debugging process.

Visualizing single table design helps you to understand how to structure your serverless applications

Figure 4. Visualizing single table design helps you to understand how to structure your serverless applications

Take me to the documentation

Instrument observability for Lambda functions with Powertools

AWS Lambda Powertools is your go-to open source project when you want to instrument observability and beyond for AWS Lambda functions. Available for multiple programming languages including Python, Node.js, Java, and .NET, Powertools empowers developers to build production-ready Lambda functions with ease. At its core, it provides comprehensive observability features, enabling structured logging, creating custom metrics, and implementing distributed tracing with minimal overhead. But Powertools doesn’t stop there – it also includes utilities for parameter store and secrets management, making it simpler to handle configuration and sensitive data. The suite offers idempotency helpers to ensure reliable execution of your functions, even in the face of retries or duplicates. With its event handler functions, Powertools streamlines the processing of various AWS events, reducing boilerplate code and potential errors. By adopting Powertools, developers can significantly reduce the time spent on implementing best practices, allowing them to focus on building business logic while ensuring their Lambda functions are performant, secure, and easily maintainable.

Powertools for Python goes over and beyond just observability as you can see by the list on the left of this screenshot

Figure 5. Powertools for Python goes over and beyond just observability as you can see by the list on the left of this screenshot

Take me to this tool

AWS Serverless developer experience workshop

The AWS Serverless Developer Experience workshop is an hands-on guide that brings together all the cutting-edge tools and techniques we’ve discussed, offering developers a holistic approach to building serverless applications. This free, self-paced workshop is designed to elevate your serverless development skills, regardless of your experience level. It covers a wide range of topics, from implementing best practices with AWS Lambda Powertools, to optimizing your functions using AWS Lambda Power Tuning. The workshop also delves into CI/CD practices, showing you how to automate your deployment pipeline for faster, more reliable releases.

The serverless developer experience architecture you will work on during the workshop

Figure 6. The serverless developer experience architecture you will work on during the workshop

Take me to the workshop

See you next time!

Thanks for reading! This is the last post of the year, thank you so much for being with us for the 3rd year in a row. To revisit any of our previous posts or explore the entire series, visit the Let’s Architect! page.

Unlocking near real-time analytics with petabytes of transaction data using Amazon Aurora Zero-ETL integration with Amazon Redshift and dbt Cloud

Post Syndicated from BP Yau original https://aws.amazon.com/blogs/big-data/unlocking-near-real-time-analytics-with-petabytes-of-transaction-data-using-amazon-aurora-zero-etl-integration-with-amazon-redshift-and-dbt-cloud/

While customers can perform some basic analysis within their operational or transactional databases, many still need to build custom data pipelines that use batch or streaming jobs to extract, transform, and load (ETL) data into their data warehouse for more comprehensive analysis.

Zero-ETL integration with Amazon Redshift reduces the need for custom pipelines, preserves resources for your transactional systems, and gives you access to powerful analytics. Within seconds of transactional data being written into Amazon Aurora (a fully managed modern relational database service offering performance and high availability at scale), the data is seamlessly made available in Amazon Redshift for analytics and machine learning. The data in Amazon Redshift is transactionally consistent and updates are automatically and continuously propagated.

Amazon Redshift is a fast, scalable, secure, and fully managed cloud data warehouse that makes it simple and cost-effective to analyze all your data using standard SQL and your existing ETL, business intelligence (BI), and reporting tools. Together with price-performance, Amazon Redshift offers capabilities such as serverless architecture, machine learning integration within your data warehouse and secure data sharing across the organization.

dbt helps manage data transformation by enabling teams to deploy analytics code following software engineering best practices such as modularity, continuous integration and continuous deployment (CI/CD), and embedded documentation.

dbt Cloud is a hosted service that helps data teams productionize dbt deployments. dbt Cloud offers turnkey support for job scheduling, CI/CD integrations; serving documentation, native git integrations, monitoring and alerting, and an integrated developer environment (IDE) all within a web-based UI.

In this post, we explore how to use Aurora MySQL-Compatible Edition Zero-ETL integration with Amazon Redshift and dbt Cloud to enable near real-time analytics. By using dbt Cloud for data transformation, data teams can focus on writing business rules to drive insights from their transaction data to respond effectively to critical, time sensitive events. This enables the line of business (LOB) to better understand their core business drivers so they can maximize sales, reduce costs, and further grow and optimize their business.

Solution overview

Let’s consider TICKIT, a fictional website where users buy and sell tickets online for sporting events, shows, and concerts. The transactional data from this website is loaded into an Aurora MySQL 3.05.0 (or a later version) database. The company’s business analysts want to generate metrics to identify ticket movement over time, success rates for sellers, and the best-selling events, venues, and seasons. Analysts can use this information to provide incentives to buyers and sellers who frequently use the site, to attract new users, and to drive advertising and promotions.

The Zero-ETL integration between Aurora MySQL and Amazon Redshift is set up by using a CloudFormation template to replicate raw ticket sales information to a Redshift data warehouse. After the data is in Amazon Redshift, dbt models are used to transform the raw data into key metrics such as ticket trends, seller performance, and event popularity. These insights help analysts make data-driven decisions to improve promotions and user engagement.

The following diagram illustrates the solution architecture at a high-level.

To implement this solution, complete the following steps:

  1. Set up Zero-ETL integration from the AWS Management Console for Amazon Relational Database Service (Amazon RDS).
  2. Create dbt models in dbt Cloud.
  3. Deploy dbt models to Amazon Redshift.

Prerequisites

Set up resources with CloudFormation

This post provides a CloudFormation template as a general guide. You can review and customize it to suit your needs. Some of the resources that this stack deploys incur costs when in use.

The CloudFormation template provisions the following components

  • An Aurora MySQL provisioned cluster (source)
  • An Amazon Redshift Serverless data warehouse (target)
  • Zero-ETL integration between the source (Aurora MySQL) and target (Amazon Redshift Serverless)

To create your resources:

  1. Sign in to the console.
  2. Choose the us-east-1 AWS Region in which to create the stack.
  3. Choose Launch Stack

       Launch Cloudformation Stack

  1. Choose Next.

This automatically launches CloudFormation in your AWS account with a template. It prompts you to sign in as needed. You can view the CloudFormation template from within the console.

  1. For Stack name, enter a stack name.
  2. Keep the default values for the rest of the Parameters and choose Next.
  3. On the next screen, choose Next.
  4. Review the details on the final screen and select I acknowledge that AWS CloudFormation might create IAM resources.
  5. Choose Submit.

Stack creation can take up to 30 minutes.

  1. After the stack creation is complete go to the Outputs tab of the stack and record the values of the keys for the following components, which you will use in a later step:
  • NamespaceName
  • PortNumber
  • RDSPassword
  • RDSUsername
  • RedshiftClusterSecurityGroupName
  • RedshiftPassword
  • RedshiftUsername
  • VPC
  • Workinggroupname
  • ZeroETLServicesRoleNameArn

  1. Configure your Amazon Redshift data warehouse security group settings to allow inbound traffic from dbt IP addresses.
  2. You’re now ready to sign in to both Aurora MySQL cluster and Amazon Redshift Serverless data warehouse and run some basic commands to test them.

Create a database from integration in Amazon Redshift

To create a target database using Redshift query editor V2:

  1. On the Amazon Redshift Serverless console, choose the zero-etl-destination workgroup.
  2. Choose Query data to open Query Editor v2.
  3. Connect to an Amazon Redshift Serverless data warehouse using the username and password from the CloudFormation resource creation step.
  4. Get the integration_id from the svv_integration system table.
select integration_id from svv_integration; ---- copy this result, use in the next sql
  1. Use the integration_id from the preceding step to create a new database from the integration.
CREATE DATABASE aurora_zeroetl_integration FROM INTEGRATION '<result from above>';

The integration between Aurora MYSQL and the Amazon Redshift Serverless data warehouse is now complete.

Populate source data in Aurora MySQL

You’re now ready to populate source data in Amazon Aurora MYSQL.

You can use your favorite query editor installed on either an Amazon Elastic Compute Cloud (Amazon EC2) instance or your local system to interact with Aurora MYSQL. However, you need to provide access to Aurora MYSQL from the machine where the query editor is installed. To achieve this, modify the security group inbound rules to allow the IP address of your machine and make Aurora publicly accessible.

To populate source data:

  1. Run the following script on Query Editor to create the sample database DEMO_DB and tables inside DEMO_DB.
create database demodb;

create table demodb.users(
userid integer not null primary key,
username char(8),
firstname varchar(30),
lastname varchar(30),
city varchar(30),
state char(2),
email varchar(100),
phone char(14),
likesports boolean,
liketheatre boolean,
likeconcerts boolean,
likejazz boolean,
likeclassical boolean,
likeopera boolean,
likerock boolean,
likevegas boolean,
likebroadway boolean,
likemusicals boolean);

create table demodb.venue(
venueid integer not null primary key,
venuename varchar(100),
venuecity varchar(30),
venuestate char(2),
venueseats integer);

create table demodb.category(
catid integer not null primary key,
catgroup varchar(10),
catname varchar(10),
catdesc varchar(50));

create table demodb.date (
dateid integer not null primary key,
caldate date not null,
day character(3) not null,
week smallint not null,
month character(5) not null,
qtr character(5) not null,
year smallint not null,
holiday boolean default FALSE );

create table demodb.event(
eventid integer not null primary key,
venueid integer not null,
catid integer not null,
dateid integer not null,
eventname varchar(200),
starttime timestamp);

create table demodb.listing(
listid integer not null primary key,
sellerid integer not null,
eventid integer not null,
dateid integer not null,
numtickets smallint not null,
priceperticket decimal(8,2),
totalprice decimal(8,2),
listtime timestamp);

create table demodb.sales(
salesid integer not null primary key,
listid integer not null,
sellerid integer not null,
buyerid integer not null,
eventid integer not null,
dateid integer not null,
qtysold smallint not null,
pricepaid decimal(8,2),
commission decimal(8,2),
saletime timestamp);
  1. Load data from Amazon Simple Storage Service (Amazon S3) to the corresponding table using the following commands:
LOAD DATA FROM S3 PREFIX 's3-us-east-1://aws-bigdata-blog/artifacts/BDB-3864/data/tickit/users/' 
INTO TABLE demodb.users FIELDS TERMINATED BY '|';

LOAD DATA FROM S3 PREFIX 's3-us-east-1://aws-bigdata-blog/artifacts/BDB-3864/data/tickit/venue/' 
INTO TABLE demodb.venue FIELDS TERMINATED BY '|';

LOAD DATA FROM S3 PREFIX 's3-us-east-1://aws-bigdata-blog/artifacts/BDB-3864/data/tickit/category/' 
INTO TABLE demodb.category FIELDS TERMINATED BY '|';

LOAD DATA FROM S3 PREFIX 's3-us-east-1://aws-bigdata-blog/artifacts/BDB-3864/data/tickit/date/' 
INTO TABLE demodb.date FIELDS TERMINATED BY '|';

LOAD DATA FROM S3 PREFIX 's3-us-east-1://aws-bigdata-blog/artifacts/BDB-3864/data/tickit/event/' 
INTO TABLE demodb.event FIELDS TERMINATED BY '|';

LOAD DATA FROM S3 PREFIX 's3-us-east-1://aws-bigdata-blog/artifacts/BDB-3864/data/tickit/listing/' 
INTO TABLE demodb.listing FIELDS TERMINATED BY '|';

LOAD DATA FROM S3 PREFIX 's3-us-east-1://aws-bigdata-blog/artifacts/BDB-3864/data/tickit/sales/' 
INTO TABLE demodb.sales FIELDS TERMINATED BY '|';

The following are common errors associated with load from Amazon S3:

  • For the current version of the Aurora MySQL cluster, set the aws_default_s3_role parameter in the database cluster parameter group to the role Amazon Resource Name (ARN) that has the necessary Amazon S3 access permissions.
  • If you get an error for missing credentials, such as the following, you probably haven’t associated your IAM role to the cluster. In this case, add the intended IAM role to the source Aurora MySQL cluster.

Error 63985 (HY000): S3 API returned error: Missing Credentials: Cannot instantiate S3 Client),

Validate the source data in your Amazon Redshift data warehouse

To validate the source data

  1. Navigate to the Redshift Serverless dashboard, open Query Editor v2, and select the workgroup and database created from integration from the drop-down list. Expand the database aurora_zeroetl, schema demodb and you should see 7 tables being created.
  2. Wait a few seconds and run the following SQL query to see integration in action.
select * from aurora_zeroetl_integration.demodb.category;

Transforming data with dbtCloud

Connect dbt Cloud to Amazon Redshift

  1. Create a new project in dbt Cloud. From Account settings (using the gear menu in the top right corner), choose + New Project.
  2. Enter a project name and choose Continue.

  1. For Connection, select Add new connection from the drop-down list.
  2. Select Redshift and enter the following information:
    1. Connection name: The Name of the connection.
    2. Server Hostname: Your Amazon Redshift Serverless endpoint.
    3. Port: Redshift 5439.
    4. Database name: dev.
  3. Make sure you allowlist your dbt Cloud IP address in your Redshift data warehouse security group inbound traffic.
  4. Choose Save to set up your connection.

  1. Set your development credentials. These credentials will be used by dbt Cloud to connect to your Amazon Redshift data warehouse. See the CloudFormation template output for the credentials.
  2. Schemadbt_zetl. dbt Cloud automatically generates a schema name for you. By convention, this is dbt_<first-initial><last-name>. This is the schema connected directly to your development environment, and it’s where your models will be built when running dbt within the Cloud integrated development environment (IDE).

  1. Choose Test Connection. This verifies that dbt Cloud can access your Redshift data warehouse.
  2. Choose Next if the test succeeded. If it failed, check your Amazon Redshift settings and credentials.

Set up a dbt Cloud managed repository

When you develop in dbt Cloud, you can use git to version control your code. For the purposes of this post, use a dbt Cloud-hosted managed repository.

To set up a managed repository:

  1. Under Setup a repository, select Managed.
  2. Enter a name for your repo, such as dbt-zeroetl.
  3. Choose Create. It will take a few seconds for your repository to be created and imported.

Initialize your dbt project and start developing

Now that you have a repository configured, initialize your project and start developing in dbt Cloud.

To start development in dbt Cloud:

  1. In dbt Cloud, choose Start developing in the IDE. It might take a few minutes for your project to spin up for the first time as it establishes your git connection, clones your repo, and tests the connection to the warehouse.

  1. Above the file tree to the left, choose Initialize dbt project. This builds out your folder structure with example models.

  1. Make your initial commit by choosing Commit and sync. Use the commit message initial commit and choose Commit Changes. This creates the first commit to your managed repo and allows you to open a branch where you can add new dbt code.

To build your models

  1. Under Version Control on the left, choose Create branch. Enter a name, such as add-redshift-models. You need to create a new branch because the main branch is set to read-only mode.
  2. Choose dbt_project.yml.
  3. Update the models section of dbt_project.yml at the bottom of the file. Change example to staging and make sure the materialized value is set to table.

models:

my_new_project:

# Applies to all files under models/example/

staging:

materialized: table

  1. Choose the three-dot icon () next to the models directory, then select Create Folder.
  2. Name the folder staging, then choose Create.
  3. Choose the three-dot icon () next to the models directory, then select Create Folder.
  4. Name the folder dept_finance, then choose Create.
  5. Choose the three-dot icon () next to the staging directory, then select Create File.

  1. Name the file sources.yml, then choose Create.
  2. Copy the following query into the file and choose Save.
version: 2
sources:
- name: ops
database: aurora_zeroetl_integration
schema: demodb
tables:
- name: category
- name: date
- name: event
- name: listing
- name: users
- name: venue
- name: sales

Be aware that the operation database created on your Amazon Redshift data warehouse is a special read only database and you cannot directly connect to it to create objects. You need to connect to another regular database and use three-part notation as defined in sources.yml to query data from it.

  1. Choose the three-dot icon () directory, then select Create File.
  2. Name the file staging_event.sql, then choose Create.
  3. Copy the following query into the file and choose Save.
with source as (
select * from {{ source('ops', 'event') }}
)
SELECT
eventid::integer AS eventid,
venueid::smallint AS venueid,
catid::smallint AS catid,
dateid::smallint AS dateid,
eventname::varchar(200) AS eventname,
starttime::timestamp AS starttime,
current_timestamp as etl_load_timestamp
from source
  1. Choose the three-dot icon ()  next to the staging directory, then select Create File.
  2. Name the file staging_sales.sql, then choose Create.
  3. Copy the following query into the file and choose Save.
with store_source as (
select * from {{ source('ops', 'sales') }}
)
SELECT
salesid::integer AS salesid,
'store' as salestype,
listid::integer AS listid,
sellerid::integer AS sellerid,
buyerid::integer AS buyerid,
eventid::integer AS eventid,
dateid::smallint AS dateid,
qtysold::smallint AS qtysold,
pricepaid::decimal(8,2) AS pricepaid,
commission::decimal(8,2) AS commission,
saletime::timestamp AS saletime,
current_timestamp as etl_load_timestamp
from store_source
  1. Choose the three-dot icon ()  next to the dept_finance directory, then select Create File.
  2. Name the file rpt_finance_qtr_total_sales_by_event.sql, then choose Create.
  3. Copy the following query into the file and choose Save.
select
date_part('year', a.saletime) as year,
date_part('quarter', a.saletime) as quarter,
b.eventname,
count(a.salesid) as sales_made,
sum(a.pricepaid) as sales_revenue,
sum(a.commission) as staff_commission,
staff_commission / sales_revenue as commission_pcnt
from {{ref('staging_sales')}} a
left join {{ref('staging_event')}} b on a.eventid = b.eventid
group by
year,
quarter,
b.eventname
order by
year,
quarter,
b.eventname
  1. Choose the three-dot icon () next to the dept_finance directory, then select Create File.
  2. Name the file rpt_finance_qtr_top_event_by_sales.sql, then choose Create.
  3. Copy the following query into the file and choose Save.
select *
from
(
select
*,
rank() over (partition by year, quarter order by sales_revenue desc) as row_num
from {{ref('rpt_finance_qtr_total_sales_by_event')}}
)
where row_num <= 3
  1. Choose the three-dot icon () next to the example directory, then select Delete.
  2. Enter dbt run in the command prompt at the bottom of the screen and press Enter.

  1. You should get a successful run and see the four models.

  1. Now that you have successfully run the dbt model, you should be able to find it in the Amazon Redshift data warehouse. Go to Redshift Query Editor v2, refresh the dev database, and verify that you have a new dbt_zetl schema with the staging_event and staging_sales tables and rpt_finance_qtr_top_event_by_sales and rpt_finance_qtr_total_sales_by_event views in it.

  1. Run the following SQL statement to verify that data has been loaded into your Amazon Redshift table.
    SELECT * FROM dbt_zetl.rpt_finance_qtr_total_sales_by_event;
    SELECT * FROM dbt_zetl.rpt_finance_qtr_top_event_by_sales;

Add tests to your models

Adding tests to a project helps validate that your models are working correctly.

To add tests to your project:

  1. Create a new YAML file in the models directory and name it models/schema.yml.
  2. Add the following contents to the file:
version: 2
models:
- name: rpt_finance_qtr_top_events_by_sales
columns:
- name: year
tests:
- not_null
- name: rpt_finance_qtr_total_sales_by_event
columns:
- name: year
tests:
- not_null
- name: staging_event
columns:
- name: eventid
tests:
- not_null
- name: staging_sales
columns:
- name: salesid
tests:
- not_null
  1. Run dbt test, and confirm that all your tests passed.
  2. When you run dbt test, dbt iterates through your YAML files and constructs a query for each test. Each query will return the number of records that fail the test. If this number is 0, then the test is successful.

Document your models

By adding documentation to your project, you can describe your models in detail and share that information with your team.

To add documentation:

  1. Run dbt docs generate to generate the documentation for your project. dbt inspects your project and your warehouse to generate a JSON file documenting your project.

  1. Choose the book icon in the Develop interface to launch documentation in a new tab.

Commit your changes

Now that you’ve built your models, you need to commit the changes you made to the project so that the repository has your latest code.

To commit the changes:

  1. Under Version Control on the left, choose Commit and sync and add a message. For example, Add Aurora zero-ETL integration with Redshift models.

  1. Choose Merge this branch to main to add these changes to the main branch on your repo.

Deploy dbt

Use dbt Cloud’s Scheduler to deploy your production jobs confidently and build observability into your processes. You’ll learn to create a deployment environment and run a job in the following steps.

To create a deployment environment:

  1. In the left pane, select Deploy, then choose Environments.

  1. Choose Create Environment.
  2. In the Name field, enter the name of your deployment environment. For example, Production.
  3. In the dbt Version field, select Versionless from the dropdown.
  4. In the Connection field, select the connection used earlier in development.
  5. Under Deployment Credentials, enter the credentials used to connect to your Redshift data warehouse. Choose Test Connection.

  1. Choose Save.

Create and run a job

Jobs are a set of dbt commands that you want to run on a schedule.

To create and run a job:

  1. After creating your deployment environment, you should be directed to the page for a new environment. If not, select Deploy in the left pane, then choose Jobs.
  2. Choose Create job and select Deploy job.
  3. Enter a Job name, such as,  Production run, and link to the environment you just created.
  4. Under Execution Settings, select Generate docs on run.
  5. Under Commands, add this command as part of your job if you don’t see them:
    • dbt build
  6. For this exercise, don’t set a schedule for your project to run—while your organization’s project should run regularly, there’s no need to run this example project on a schedule. Scheduling a job is sometimes referred to as deploying a project.

  1. Choose Save, then choose Run now to run your job.
  2. Choose the run and watch its progress under Run history.
  3. After the run is complete, choose View Documentation to see the docs for your project.

Clean up

When you’re finished, delete the CloudFormation stack since some of the AWS resources in this walkthrough incur a cost if you continue to use them. Complete the following steps:

  1. On the CloudFormation console, choose Stacks.
  2. Choose the stack you launched in this walkthrough. The stack must be currently running.
  3. In the stack details pane, choose Delete.
  4. Choose Delete stack.

Summary

In this post, we showed you how to set up Amazon Aurora MySQL Zero-ETL integration from Aurora MySQL to Amazon Redshift, which eliminates complex data pipelines and enables near real-time analytics on transactional and operational data. We also showed you how to build dbt models on Aurora MySQL Zero-ETL integration tables in Amazon Redshift to transform the data to get insight.

We look forward to hearing from you about your experience. If you have questions or suggestions, leave a comment.


About the authors

BP Yau is a Sr Partner Solutions Architect at AWS. His role is to help customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.
Saman Irfan is a Senior Specialist Solutions Architect at Amazon Web Services, based in Berlin, Germany. She collaborates with customers across industries to design and implement scalable, high-performance analytics solutions using cloud technologies. Saman is passionate about helping organizations modernize their data architectures and unlock the full potential of their data to drive innovation and business transformation. Outside of work, she enjoys spending time with her family, watching TV series, and staying updated with the latest advancements in technology.

Raghu Kuppala is an Analytics Specialist Solutions Architect experienced working in the databases, data warehousing, and analytics space. Outside of work, he enjoys trying different cuisines and spending time with his family and friends.

Neela Kulkarni is a Solutions Architect with Amazon Web Services. She primarily serves independent software vendors in the Northeast US, providing architectural guidance and best practice recommendations for new and existing workloads. Outside of work, she enjoys traveling, swimming, and spending time with her family.

Announcing updates to the AWS Well-Architected Framework guidance

Post Syndicated from Haleh Najafzadeh original https://aws.amazon.com/blogs/architecture/announcing-updates-to-the-aws-well-architected-framework-guidance-3/

We are excited to announce the availability of enhanced and expanded guidance for the AWS Well-Architected Framework with the following six pillars: Operational ExcellenceSecurityReliabilityPerformance EfficiencyCost Optimization, and Sustainability

This release includes new best practices and improved prescriptive implementation guidance for the existing best practices. This includes enhanced recommendations and steps on reusable architecture patterns focused on specific business outcomes.

A brief history

The Well-Architected Framework is a collection of best practices that allow customers to evaluate and improve the design, implementation, and operations of their workloads in the cloud.

2024 AWS Well-Architected guidance timeline

Figure 1. 2024 AWS Well-Architected guidance timeline

In 2012, we published the first version of the Framework. In 2015, we released the AWS Well-Architected Framework whitepaper. We added the Operational Excellence pillar in 2016. We released the pillar-specific whitepapers and AWS Well-Architected Lenses in 2017. The following year, the AWS Well-Architected Tool was launched.

In 2020, we released the new version of the Well-Architected Framework guidance, more lenses, and an API integration with the AWS Well-Architected Tool. We added the sixth pillar, Sustainability in 2021. In 2022, dedicated pages were introduced for each consolidated best practices across all six pillars, with several best practices updated with improved prescriptive guidance. By December 2023, we improved more than 75% of the Framework’s best practices. As of November 2024, we’ve refreshed 100% of the Framework’s best practices at least once since October 2022.

What’s new

The Well-Architected Framework supports customers as they mature in their cloud journey by providing guidance to help achieve more operable, secure, sustainable, scalable, and resilient environment and workload solutions.

The content updates and prescriptive guidance improvements in this release provide more complete coverage across AWS, helping customers make informed decisions when developing implementation plans. We added or expanded on guidance for the following services in this update: Amazon API Gateway, Amazon CloudFront, Amazon CloudWatch, Amazon CodeGuru, Amazon Cognito, Amazon GuardDuty, Amazon Inspector, Amazon Macie, Amazon Q Business, Amazon Q Developers, Amazon Redshift, Amazon S3, AWS Certificate Manager, AWS CloudFormation, AWS CloudTrail, AWS CodeBuild, AWS CodeDeploy, AWS CodePipeline, AWS Config, AWS Control Tower, AWS Customer Carbon Footprint Tool, AWS Glue, AWS Health, AWS Identity and Access Management (IAM), AWS Key Management Service (KMS), AWS OpenSearch, AWS Organizations, AWS Resource Access Manager, AWS Secrets Manager, AWS Security Hub, AWS Step Functions, AWS Systems Manager, AWS Trusted Advisor, AWS Verified Access, and AWS WAF.

Pillar updates

Operational Excellence

In the Operational Excellence Pillar, we updated five best practices across four questions. This includes OPS02, OPS05, OPS09, and OPS10. The updates in this release include improved prescriptive guidance on multiple AWS services. OPS02-BP02 updates leverage Amazon Q Business for improving workforce collaboration and productivity. OPS05-BP08 updates demonstrate AWS Organizations and AWS Control Tower capabilities that enable updates to a multi-environment setup while meeting governance and policy requirements. OPS09-BP01 and OPS09-BP02 have updated guidance and resources for developing operational key performance indicators (KPIs). OPS10-BP02 has been updated with information on AWS Health, including its planned lifecycle events feature, for integrating into an incident management workflow.

Security

In the Security Pillar, we updated 43 best practices across nine questions. This includes SEC02, SEC03, SEC04, SEC06, SEC07, SEC08, SEC09, SEC10, and SEC11. All best practices in SEC03 (Permissions management) were revised, with updates to guidance on Attribute Based Access Control (ABAC), AWS IAM Access Analyzer, and emergency access processes. SEC02 (Identity management) also saw updates to all six of its best practices, including refinements to guidance on identity federation and secrets management. SEC07 through SEC11 received updates to guidance on data protection, incident response, and application security. Key updates include replacing the security information and event management SIEM solution on AWS OpenSearch recommendation with AWS CloudTrail Lake in SEC04 (Detection), expanded guidance on AWS S3 Object Lock and AWS S3 Glacier Vault Lock in SEC08 (Protecting data at rest), and the addition of recommendations for Mutual Transport Layer Security (mTLS) and private certificates in SEC09 (Protecting data in transit). Overall, these changes reflect AWS’s commitment to providing up-to-date, comprehensive security guidance in line with evolving best practices and new service capabilities.

Reliability

In the Reliability Pillar, we updated 14 best practices across nine questions. This includes REL01, REL02, REL04, REL06, REL07, REL08, REL10, REL12, and REL13. We expanded and clarified our guidance throughout the Pillar and added detailed implementation steps to each best practice that did not previously have them. We refreshed our multi-location deployment guidance by merging REL10-BP02 into REL10-BP01, while improving the prescriptive guidance of this best practice with a new title of Deploy the workload to multiple locations. We updated our idempotent operations guidance in REL04-BP04 to provide detailed technical guidance for builders who wish to provide idempotent APIs and updated the title to Make mutating operations idempotent. We merged functional testing guidance by migrating the content previously published under REL12-BP03 to REL08-BP02 (Integrate functional testing as part of your deployment) and expanded our guidance on testing in CI/CD pipelines. We refreshed REL07-BP01 to emphasize infrastructure as code (IaC) as a cornerstone of automated resource management and scaling. We improved our guidance in REL06-BP02 on how to use system and application logs to improve workload observability. We also refreshed our links to relevant resources including documents, videos, and presentations.

Performance Efficiency

In the Performance Efficiency Pillar, we updated the resources of PERF03-BP04 with the latest services.

Sustainability

In the Sustainability Pillar, we updated 10 best practices across six questions. This includes SUS01, SUS03, SUS04, SUS05, and SUS06. Best practices SUS01-BP01, SUS03-BP02, SUS03-BP05, SUS04-BP03, SUS04-BP05, SUS04-BP06, SUS04-BP07, SUS04-BP08, SUS05-BP04, and SUS06-BP02 now offer improved prescriptive guidance. Additionally, we added a new best practice, SUS06-BP01 Communicate and cascade your sustainability goals, which highlights the critical role of the central IT team in cascading sustainability goals and objectives across the broader organization. By strategically leveraging the cloud, implementing resource-efficient practices, and employing sustainability-focused tools and analytics, IT teams can play a pivotal role in driving meaningful reductions in the organization’s environmental impact.

Conclusion

This release includes updates and improvements to the Framework guidance totaling 78 best practices. As of this release, we’ve updated 100% of the existing Framework best practices at least once since October 2022. With this release, we have refreshed 100% of all the pillars of the Framework including the Reliability Pillar, with 14 of its best practice updated for the first time since major Framework improvements started in 2022.

Updates in this release will be incorporated into the AWS Well-Architected Tool in future releases, which you can use to review your workloads, address important design considerations, and help you follow the AWS Well-Architected Framework guidance.

The content will be available in 11 languages: English, Spanish, French, German, Italian, Japanese, Korean, Indonesian, Brazilian Portuguese, Simplified Chinese, and Traditional Chinese.

Ready to get started? Review the updated AWS Well-Architected Framework Pillar best practices and pillar-specific whitepapers.

Have questions about some of the new best practices or most recent updates? Join our growing community on AWS re:Post.