Tag Archives: serverless

Token-based authentication for iOS applications with Amazon SNS

Post Syndicated from Talia Nassi original https://aws.amazon.com/blogs/compute/token-based-authentication-for-ios-applications-with-amazon-sns/

This post is co-written by Karen Hong, Software Development Engineer, AWS Messaging.

To use Amazon SNS to send mobile push notifications, you must provide a set of credentials for connecting to the supported push notification service (see prerequisites for push). For the Apple Push Notification service (APNs), SNS now supports using token-based authentication (.p8), in addition to the existing certificate-based method.

You can now use a .p8 file to create or update a platform application resource through the SNS console or programmatically. You can publish messages (directly or from a topic) to platform application endpoints configured for token-based authentication.

In this tutorial, you set up an example iOS application. You retrieve information from your Apple developer account and learn how to register a new signing key. Next, you use the SNS console to set up a platform application and a platform endpoint. Finally, you test the setup and watch a push notification arrive on your device.

Advantages of token-based authentication

Token-based authentication has several benefits compared to using certificates. The first is that you can use the same signing key from multiple provider servers (iOS,VoIP, and MacOS), and you can use one signing key to distribute notifications for all of your company’s application environments (sandbox, production). In contrast, a certificate is only associated with a particular subset of these channels.

A pain point for customers using certificate-based authentication is the need to renew certificates annually, an inconvenient procedure which can lead to production issues when forgotten. Your signing key for token-based authentication, on the other hand, does not expire.

Token-based authentication improves the security of your certificates. Unlike certificate-based authentication, the credential does not transfer. Hence, it is less likely to be compromised. You establish trust through encrypted tokens that are frequently regenerated. SNS manages the creation and management of these tokens.

You configure APNs platform applications for use with both .p8 and .p12 certificates, but only 1 authentication method is active at any given time.

Setting up your iOS application

To use token-based authentication, you must set up your application.

Prerequisites: An Apple developer account

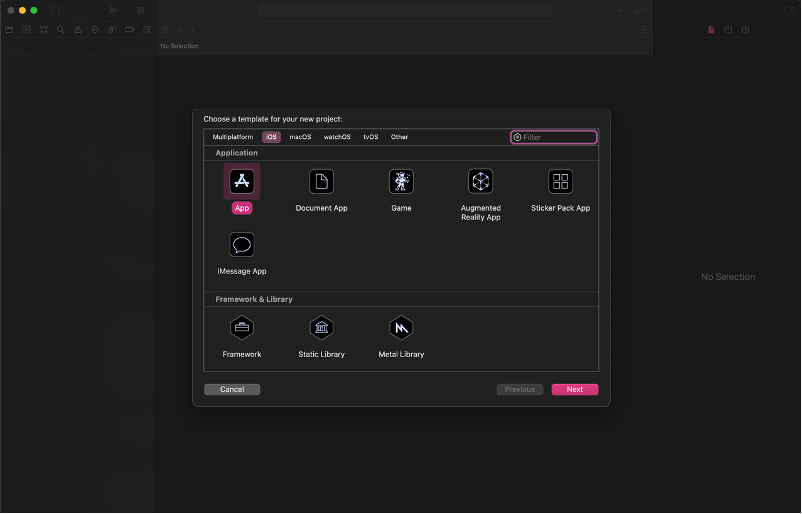
  1. Create a new XCode project. Select iOS as the platform and use the App template.
    xcode project
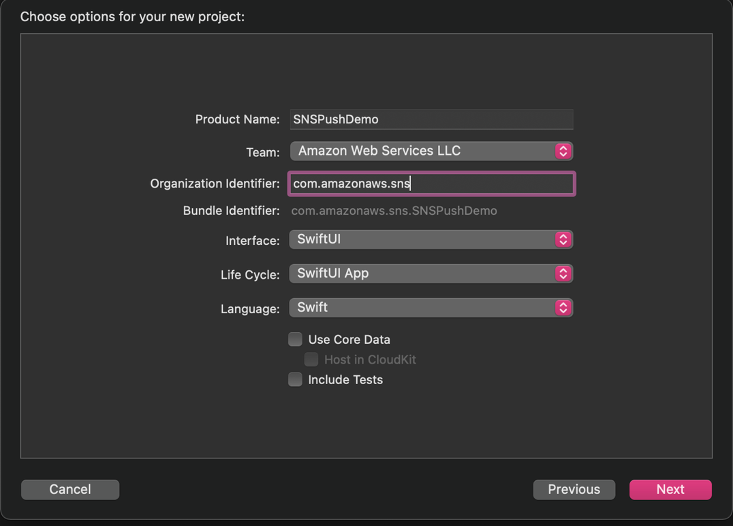
  2. Select your Apple Developer Account team and your organization identifier.
    vscode details
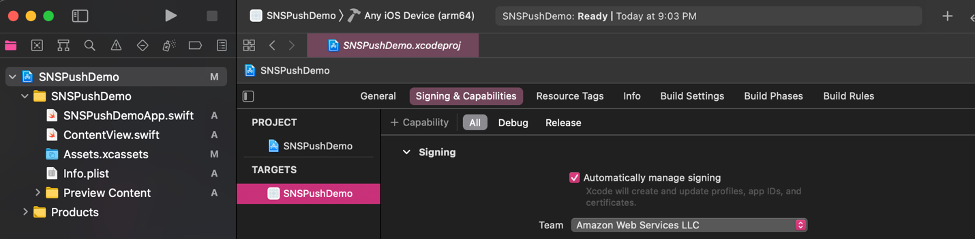
  3. Go to Signing & Capabilities and select + Capability. This step creates resources on your Apple Developer Account.
    step 3
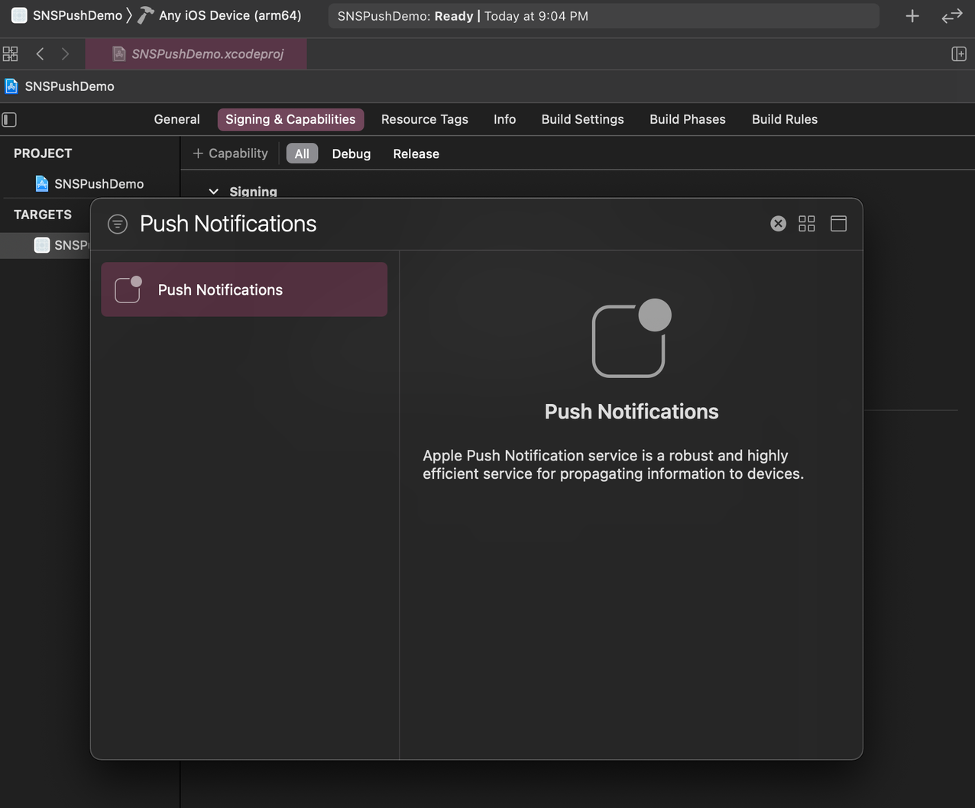
  4. Add the Push Notification Capability.
  5. In SNSPushDemoApp.swift , add the following code to print the device token and receive push notifications.
    import SwiftUI
    
    @main
    struct SNSPushDemoApp: App {
        
        @UIApplicationDelegateAdaptor private var appDelegate: AppDelegate
        
        var body: some Scene {
            WindowGroup {
                ContentView()
            }
        }
    }
    
    class AppDelegate: NSObject, UIApplicationDelegate, UNUserNotificationCenterDelegate {
        
        func application(_ application: UIApplication,
                         didFinishLaunchingWithOptions launchOptions: [UIApplication.LaunchOptionsKey : Any]? = nil) -> Bool {
            UNUserNotificationCenter.current().delegate = self
            return true
        }
        
        func application(_ application: UIApplication,
                         didRegisterForRemoteNotificationsWithDeviceToken deviceToken: Data) {
            let tokenParts = deviceToken.map { data in String(format: "%02.2hhx", data) }
            let token = tokenParts.joined()
            print("Device Token: \(token)")
        };
        
        func application(_ application: UIApplication, didFailToRegisterForRemoteNotificationsWithError error: Error) {
           print(error.localizedDescription)
        }
        
        func userNotificationCenter(_ center: UNUserNotificationCenter, willPresent notification: UNNotification, withCompletionHandler completionHandler: @escaping (UNNotificationPresentationOptions) -> Void) {
            completionHandler([.banner, .badge, .sound])
        }
    }
    
  6. In ContentView.swift, add the code to request authorization for push notifications and register for notifications.
    import SwiftUI
    
    struct ContentView: View {
        init() {
            requestPushAuthorization();
        }
        
        var body: some View {
            Button("Register") {
                registerForNotifications();
            }
        }
    }
    
    struct ContentView_Previews: PreviewProvider {
        static var previews: some View {
            ContentView()
        }
    }
    
    func requestPushAuthorization() {
        UNUserNotificationCenter.current().requestAuthorization(options: [.alert, .badge, .sound]) { success, error in
            if success {
                print("Push notifications allowed")
            } else if let error = error {
                print(error.localizedDescription)
            }
        }
    }
    
    func registerForNotifications() {
        UIApplication.shared.registerForRemoteNotifications()
    }
    
  7. Build and run the app on an iPhone. The push notification feature does not work with a simulator.
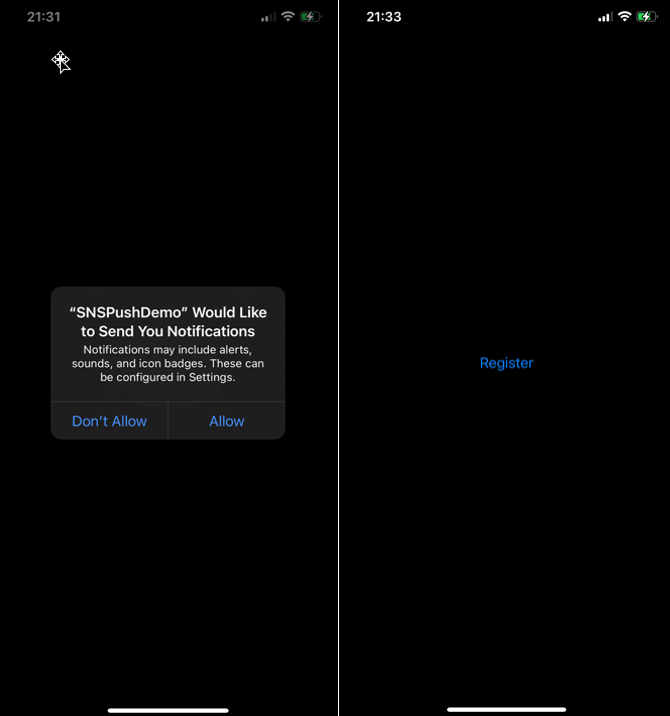
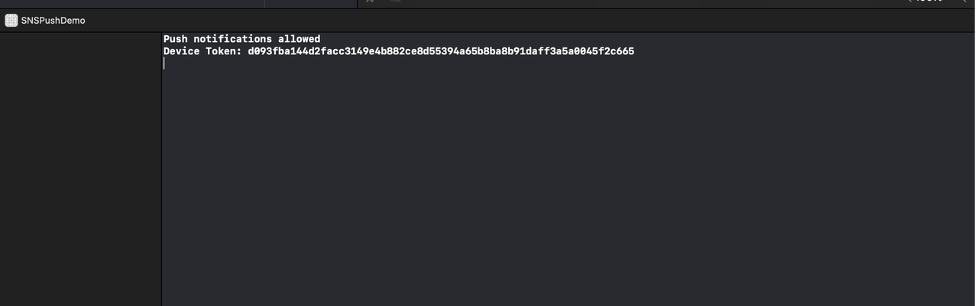
  8. On your phone, select allow notifications when the prompt appears. The debugger prints out “Push notifications allowed” if it is successful.
    allow notifications
  9. On your phone, choose the Register button. The debugger prints out the device token.
  10. You have set up an iOS application that can receive push notifications and prints the device token. We can now use this app to test sending push notifications with SNS configured for token-based authentication.
Retrieving your Apple resources

After setting up your application, you retrieve your Apple resources from your Apple developer account. There are four pieces of information you need from your Apple Developer Account: Bundle ID, Team ID, Signing Key, and Signing Key ID.

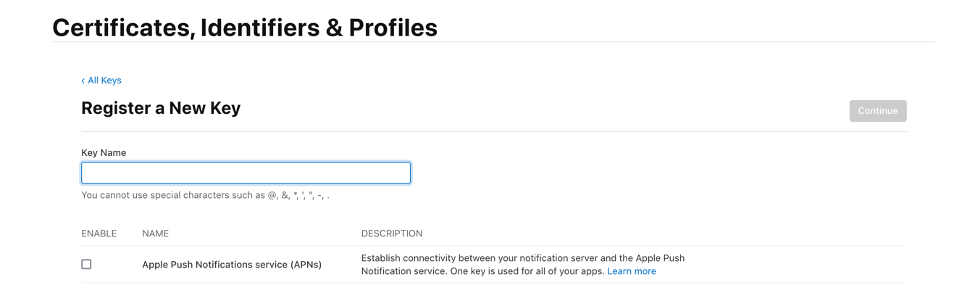
The signing key and signing key ID are credentials that you manage through your Apple Developer Account. You can register a new key by selecting the Keys tab under the Certificates, Identifiers & Profiles menu. Your Apple developer account provides the signing key in the form of a text file with a .p8 extension.
certs

Find the team ID under Membership Details. The bundle ID is the unique identifier that you set up when creating your application. Find this value in the Identifiers section under the Certificates, Identifiers & Profiles menu.

Amazon SNS uses a token constructed from the team ID, signing key, and signing key ID to authenticate with APNs for every push notification that you send. Amazon SNS manages tokens on your behalf and renews them when necessary (within an hour). The request header includes the bundle ID and helps identify where the notification goes.

Creating a new platform application using APNs token-based authentication

Prerequisites

In order to implement APNs token-based authentication, you must have:

  • An Apple Developer Account
  • A mobile application

To create a new platform application:

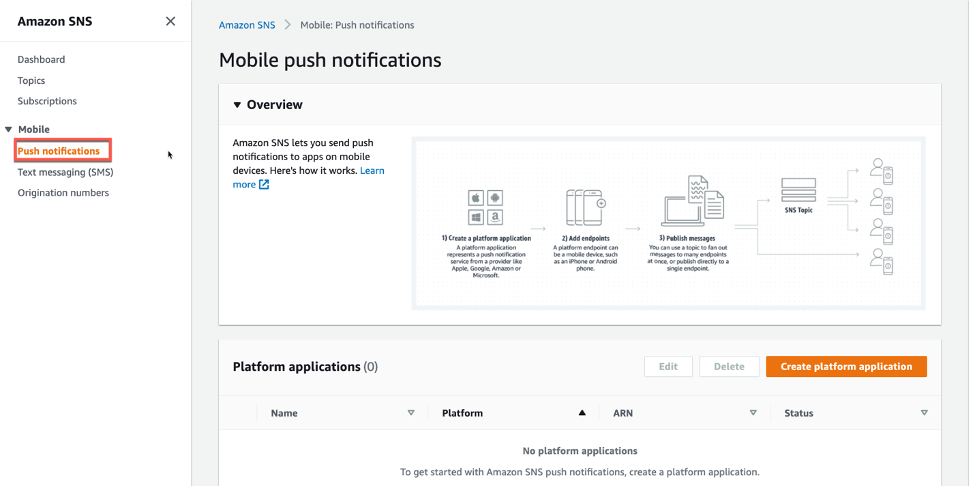
  1. Navigate to the Amazon SNS console and choose Push notifications. Then choose Create platform application.
    sns console
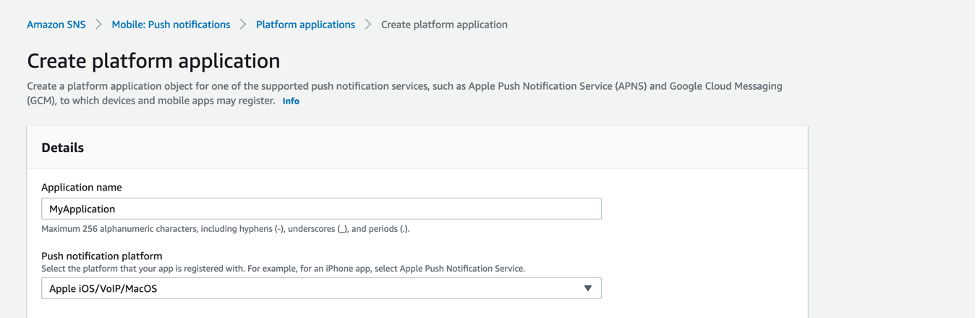
  2. Enter a name for your application. In the Push notification platform dropdown, choose Apple iOS/VoIP/Mac.
    sns name
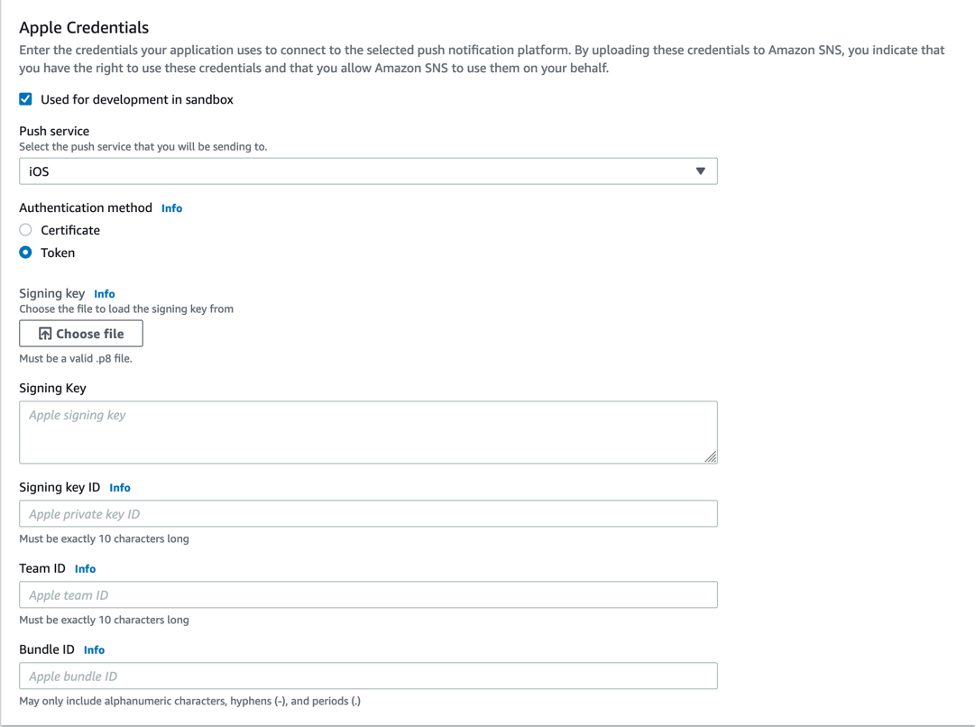
  3. For the Push service, choose iOS, and for the Authentication method, choose Token. Select the check box labeled Used for development in sandbox. Then, input the fields from your Apple Developer Account.
    step 3
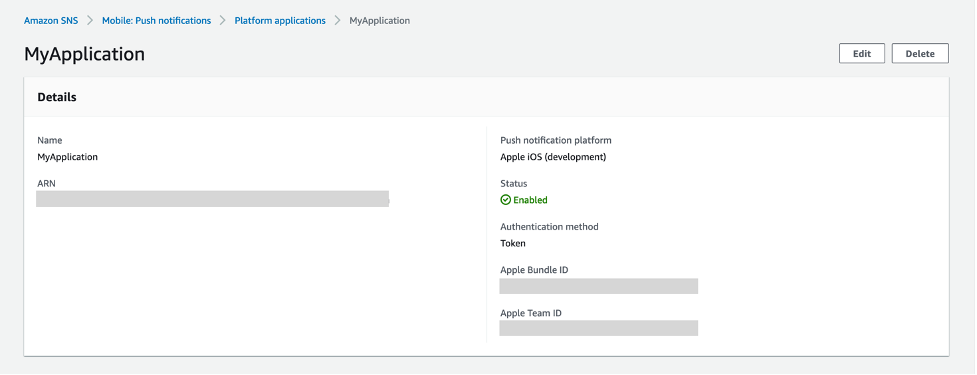
  4. You have successfully created a platform application using APNs token-based authentication.

Creating a new platform endpoint using APNs token-based authentication

A platform application stores credentials, sending configuration, and other settings but does not contain an exact sending destination. Create a platform endpoint resource to store the information to allow SNS to target push notifications to the proper application on the correct mobile device.

Any iOS application that is capable of receiving push notifications must register with APNs. Upon successful registration, APNs returns a device token that uniquely identifies an instance of an app. SNS needs this device token in order to send to that app. Each platform endpoint belongs to a specific platform application and uses the credentials and settings set in the platform application to complete the sending.

In this tutorial, you create the platform endpoint manually through the SNS console. In a real system, upon receiving the device token, you programmatically call SNS from your application server to create or update your platform endpoints.

These are the steps to create a new platform endpoint:

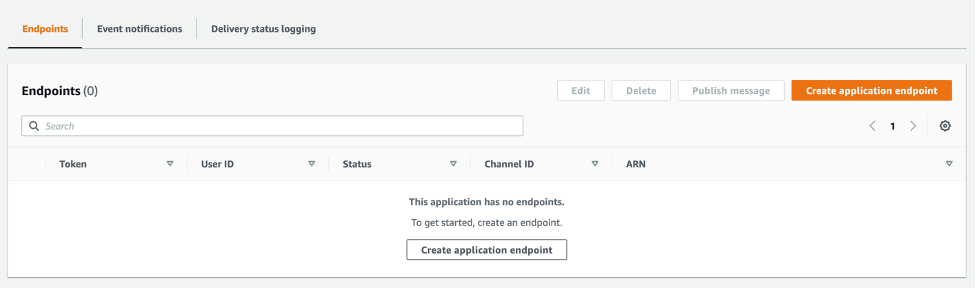
  1. From the details page of the platform application in the SNS console, choose Create application endpoint.
    appliation endpont
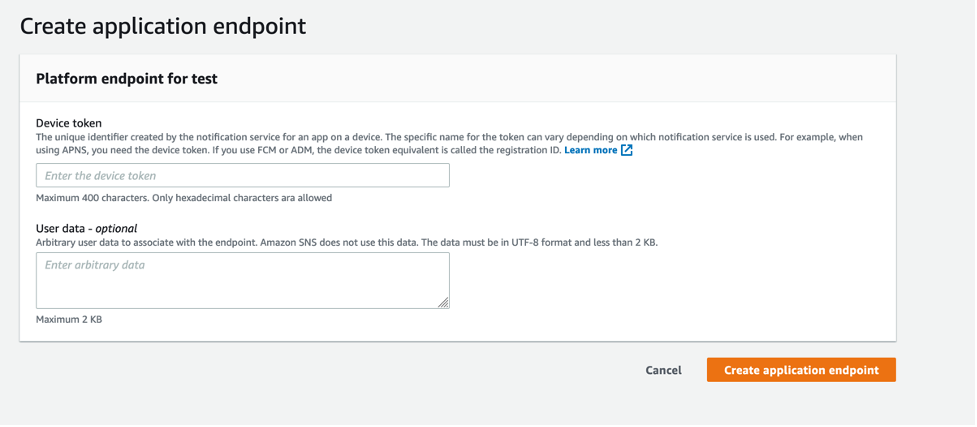
  2. From the iOS app that you set up previously, find the device token in the application logs. Enter the device token and choose Create application endpoint.
    application endpont details
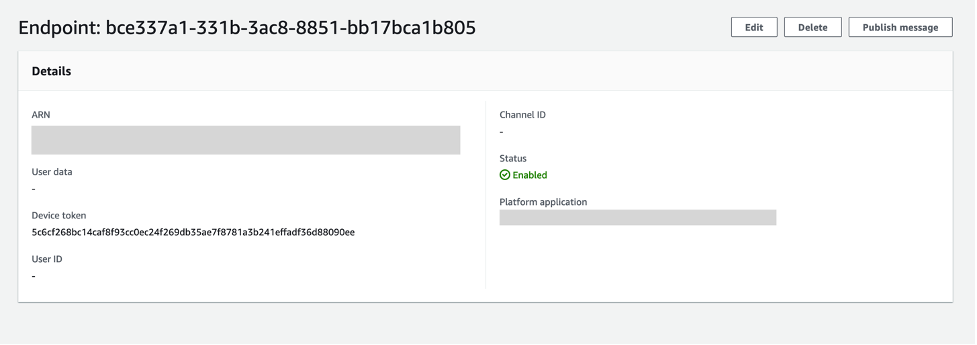
  3. You have successfully created a platform application endpoint.
    application endpoint

Testing a push notification from your device

In this section, you test a push notification from your device.

  1. From the details page of the application endpoint you just created, (this is the page you end up at immediately after creating the endpoint), choose Publish message.
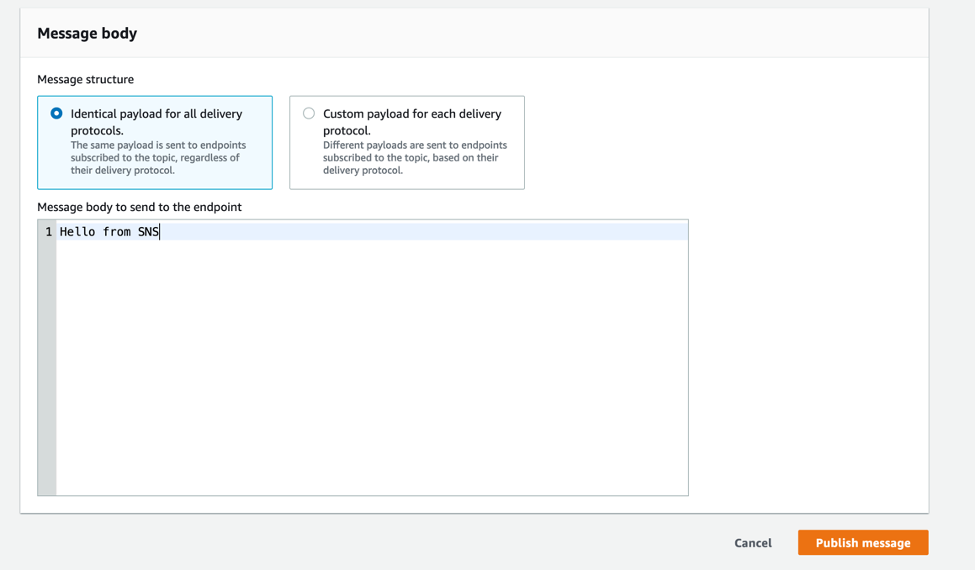
  2. Enter a message to send and choose Publish message.
    testing app
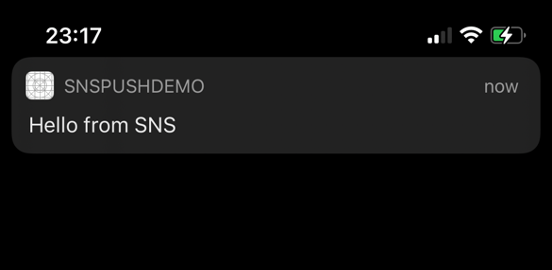
  3. The notification arrives on your iOS app.
    testing the app

Conclusion

Developers sending mobile push notifications can now use a .p8 key to authenticate an Apple device endpoint. Token-based authentication is more secure, and reduces operational burden of renewing the certificates every year. In this post, you learn how to set up your iOS application for mobile push using token-based authentication, by creating and configuring a new platform endpoint in the Amazon SNS console.

To learn more about APNs token-based authentication with Amazon SNS, visit the Amazon SNS Developer Guide. For more serverless content, visit Serverless Land.
Create a serverless event-driven workflow to ingest and process Microsoft data with AWS Glue and Amazon EventBridge

Post Syndicated from Venkata Sistla original https://aws.amazon.com/blogs/big-data/create-a-serverless-event-driven-workflow-to-ingest-and-process-microsoft-data-with-aws-glue-and-amazon-eventbridge/

Microsoft SharePoint is a document management system for storing files, organizing documents, and sharing and editing documents in collaboration with others. Your organization may want to ingest SharePoint data into your data lake, combine the SharePoint data with other data that’s available in the data lake, and use it for reporting and analytics purposes. AWS Glue is a serverless data integration service that makes it easy to discover, prepare, and combine data for analytics, machine learning, and application development. AWS Glue provides all the capabilities needed for data integration so that you can start analyzing your data and putting it to use in minutes instead of months.

Organizations often manage their data on SharePoint in the form of files and lists, and you can use this data for easier discovery, better auditing, and compliance. SharePoint as a data source is not a typical relational database and the data is mostly semi structured, which is why it’s often difficult to join the SharePoint data with other relational data sources. This post shows how to ingest and process SharePoint lists and files with AWS Glue and Amazon EventBridge, which enables you to join other data that is available in your data lake. We use SharePoint REST APIs with a standard open data protocol (OData) syntax. OData advocates a standard way of implementing REST APIs that allows for SQL-like querying capabilities. OData helps you focus on your business logic while building RESTful APIs without having to worry about the various approaches to define request and response headers, query options, and so on.

AWS Glue event-driven workflows

Unlike a traditional relational database, SharePoint data may or may not change frequently, and it’s difficult to predict the frequency at which your SharePoint server generates new data, which makes it difficult to plan and schedule data processing pipelines efficiently. Running data processing frequently can be expensive, whereas scheduling pipelines to run infrequently can deliver cold data. Similarly, triggering pipelines from an external process can increase complexity, cost, and job startup time.

AWS Glue supports event-driven workflows, a capability that lets developers start AWS Glue workflows based on events delivered by EventBridge. The main reason to choose EventBridge in this architecture is because it allows you to process events, update the target tables, and make information available to consume in near-real time. Because frequency of data change in SharePoint is unpredictable, using EventBridge to capture events as they arrive enables you to run the data processing pipeline only when new data is available.

To get started, you simply create a new AWS Glue trigger of type EVENT and place it as the first trigger in your workflow. You can optionally specify a batching condition. Without event batching, the AWS Glue workflow is triggered every time an EventBridge rule matches, which may result in multiple concurrent workflows running. AWS Glue protects you by setting default limits that restrict the number of concurrent runs of a workflow. You can increase the required limits by opening a support case. Event batching allows you to configure the number of events to buffer or the maximum elapsed time before firing the particular trigger. When the batching condition is met, a workflow run is started. For example, you can trigger your workflow when 100 files are uploaded in Amazon Simple Storage Service (Amazon S3) or 5 minutes after the first upload. We recommend configuring event batching to avoid too many concurrent workflows, and optimize resource usage and cost.

To illustrate this solution better, consider the following use case for a wine manufacturing and distribution company that operates across multiple countries. They currently host all their transactional system’s data on a data lake in Amazon S3. They also use SharePoint lists to capture feedback and comments on wine quality and composition from their suppliers and other stakeholders. The supply chain team wants to join their transactional data with the wine quality comments in SharePoint data to improve their wine quality and manage their production issues better. They want to capture those comments from the SharePoint server within an hour and publish that data to a wine quality dashboard in Amazon QuickSight. With an event-driven approach to ingest and process their SharePoint data, the supply chain team can consume the data in less than an hour.

Overview of solution

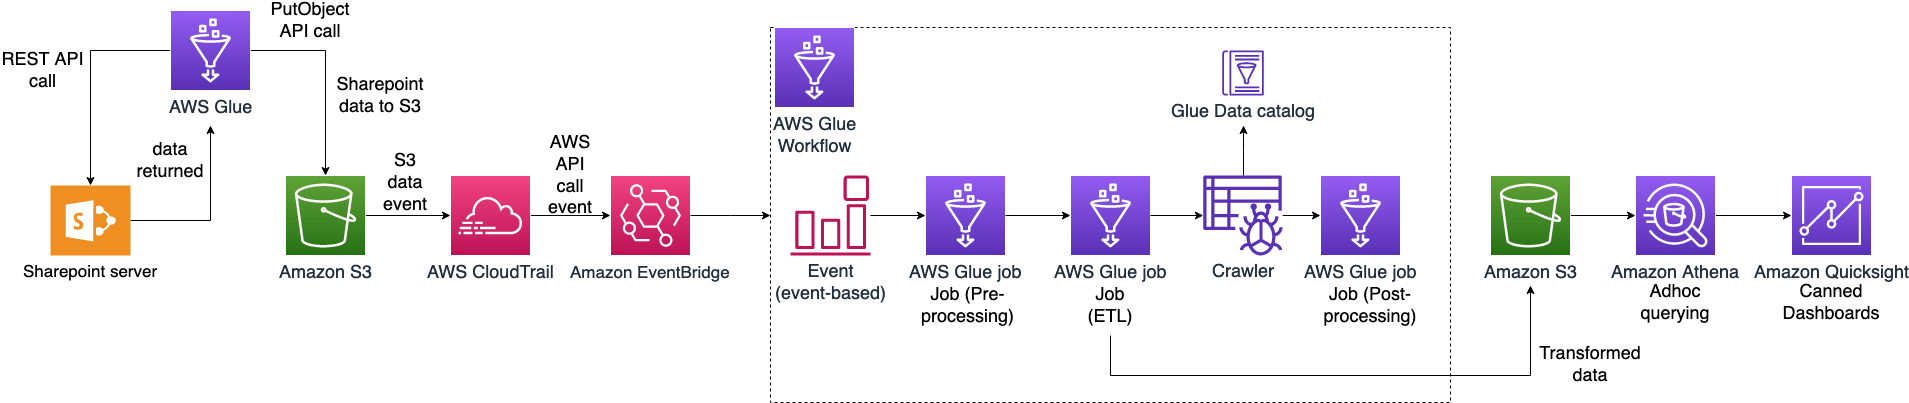
In this post, we walk through a solution to set up an AWS Glue job to ingest SharePoint lists and files into an S3 bucket and an AWS Glue workflow that listens to S3 PutObject data events captured by AWS CloudTrail. This workflow is configured with an event-based trigger to run when an AWS Glue ingest job adds new files into the S3 bucket. The following diagram illustrates the architecture.

To make it simple to deploy, we captured the entire solution in an AWS CloudFormation template that enables you to automatically ingest SharePoint data into Amazon S3. SharePoint uses ClientID and TenantID credentials for authentication and uses Oauth2 for authorization.

The template helps you perform the following steps:

  1. Create an AWS Glue Python shell job to make the REST API call to the SharePoint server and ingest files or lists into Amazon S3.
  2. Create an AWS Glue workflow with a starting trigger of EVENT type.
  3. Configure CloudTrail to log data events, such as PutObject API calls to CloudTrail.
  4. Create a rule in EventBridge to forward the PutObject API events to AWS Glue when they’re emitted by CloudTrail.
  5. Add an AWS Glue event-driven workflow as a target to the EventBridge rule. The workflow gets triggered when the SharePoint ingest AWS Glue job adds new files to the S3 bucket.

Prerequisites

For this walkthrough, you should have the following prerequisites:

Configure SharePoint server authentication details

Before launching the CloudFormation stack, you need to set up your SharePoint server authentication details, namely, TenantID, Tenant, ClientID, ClientSecret, and the SharePoint URL in AWS Systems Manager Parameter Store of the account you’re deploying in. This makes sure that no authentication details are stored in the code and they’re fetched in real time from Parameter Store when the solution is running.

To create your AWS Systems Manager parameters, complete the following steps:

  1. On the Systems Manager console, under Application Management in the navigation pane, choose Parameter Store.
    systems manager
  2. Choose Create Parameter.
  3. For Name, enter the parameter name /DATALAKE/GlueIngest/SharePoint/tenant.
  4. Leave the type as string.
  5. Enter your SharePoint tenant detail into the value field.
  6. Choose Create parameter.
  7. Repeat these steps to create the following parameters:
    1. /DataLake/GlueIngest/SharePoint/tenant
    2. /DataLake/GlueIngest/SharePoint/tenant_id
    3. /DataLake/GlueIngest/SharePoint/client_id/list
    4. /DataLake/GlueIngest/SharePoint/client_secret/list
    5. /DataLake/GlueIngest/SharePoint/client_id/file
    6. /DataLake/GlueIngest/SharePoint/client_secret/file
    7. /DataLake/GlueIngest/SharePoint/url/list
    8. /DataLake/GlueIngest/SharePoint/url/file

Deploy the solution with AWS CloudFormation

For a quick start of this solution, you can deploy the provided CloudFormation stack. This creates all the required resources in your account.

The CloudFormation template generates the following resources:

  • S3 bucket – Stores data, CloudTrail logs, job scripts, and any temporary files generated during the AWS Glue extract, transform, and load (ETL) job run.
  • CloudTrail trail with S3 data events enabled – Enables EventBridge to receive PutObject API call data in a specific bucket.
  • AWS Glue Job – A Python shell job that fetches the data from the SharePoint server.
  • AWS Glue workflow – A data processing pipeline that is comprised of a crawler, jobs, and triggers. This workflow converts uploaded data files into Apache Parquet format.
  • AWS Glue database – The AWS Glue Data Catalog database that holds the tables created in this walkthrough.
  • AWS Glue table – The Data Catalog table representing the Parquet files being converted by the workflow.
  • AWS Lambda function – The AWS Lambda function is used as an AWS CloudFormation custom resource to copy job scripts from an AWS Glue-managed GitHub repository and an AWS Big Data blog S3 bucket to your S3 bucket.
  • IAM roles and policies – We use the following AWS Identity and Access Management (IAM) roles:
    • LambdaExecutionRole – Runs the Lambda function that has permission to upload the job scripts to the S3 bucket.
    • GlueServiceRole – Runs the AWS Glue job that has permission to download the script, read data from the source, and write data to the destination after conversion.
    • EventBridgeGlueExecutionRole – Has permissions to invoke the NotifyEvent API for an AWS Glue workflow.
    • IngestGlueRole – Runs the AWS Glue job that has permission to ingest data into the S3 bucket.

To launch the CloudFormation stack, complete the following steps:

  1. Sign in to the AWS CloudFormation console.
  2. Choose Launch Stack:
  3. Choose Next.
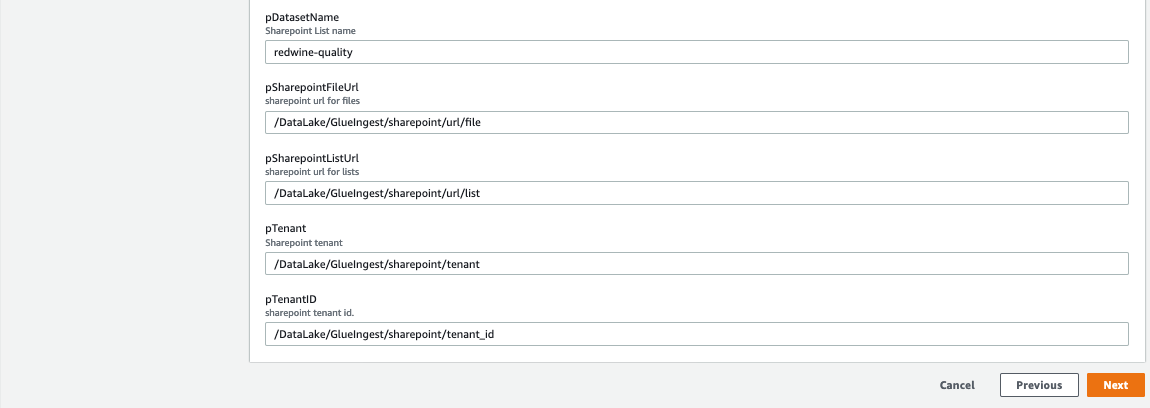
  4. For pS3BucketName, enter the unique name of your new S3 bucket.
  5. Leave pWorkflowName and pDatabaseName as the default.

cloud formation 1

  1. For pDatasetName, enter the SharePoint list name or file name you want to ingest.
  2. Choose Next.

cloud formation 2

  1. On the next page, choose Next.
  2. Review the details on the final page and select I acknowledge that AWS CloudFormation might create IAM resources.
  3. Choose Create.

It takes a few minutes for the stack creation to complete; you can follow the progress on the Events tab.

You can run the ingest AWS Glue job either on a schedule or on demand. As the job successfully finishes and ingests data into the raw prefix of the S3 bucket, the AWS Glue workflow runs and transforms the ingested raw CSV files into Parquet files and loads them into the transformed prefix.

Review the EventBridge rule

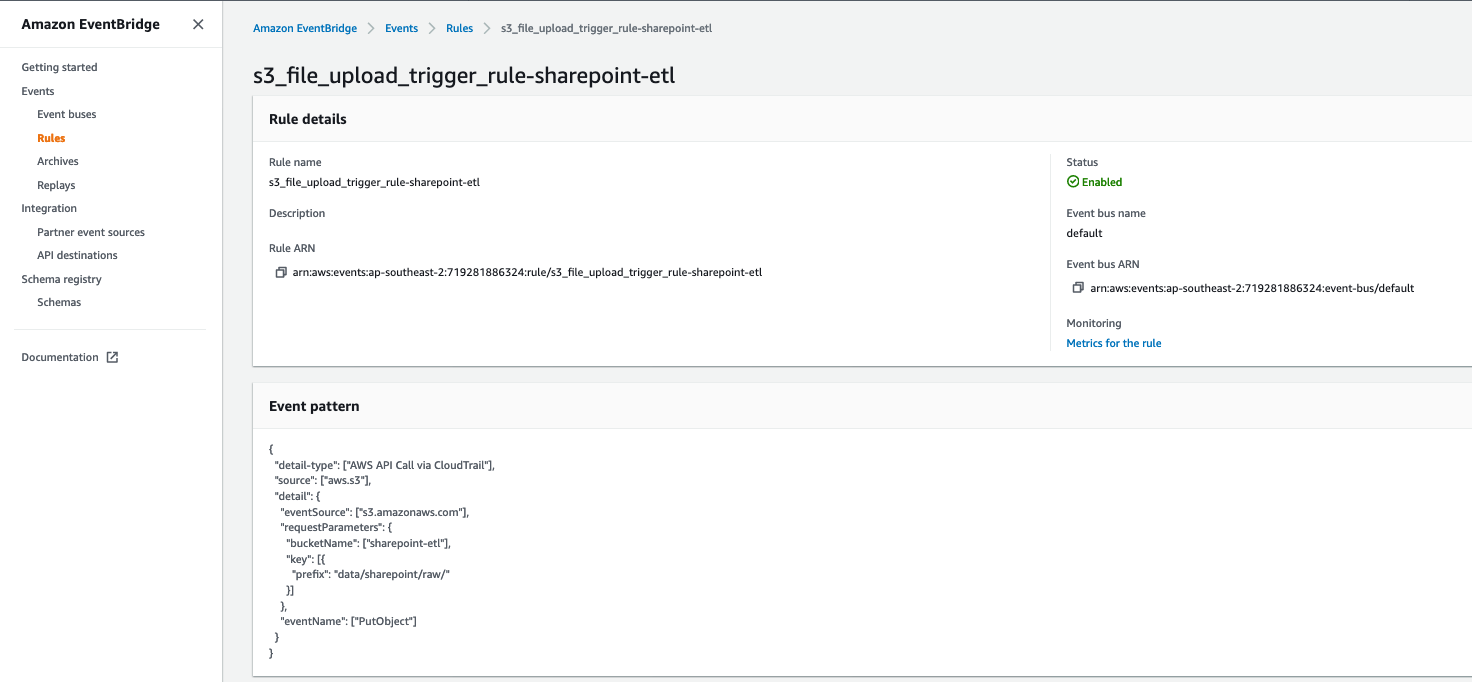
The CloudFormation template created an EventBridge rule to forward S3 PutObject API events to AWS Glue. Let’s review the configuration of the EventBridge rule:

  1. On the EventBridge console, under Events, choose Rules.
  2. Choose the rule s3_file_upload_trigger_rule-<CloudFormation-stack-name>.
  3. Review the information in the Event pattern section.

event bridge

The event pattern shows that this rule is triggered when an S3 object is uploaded to s3://<bucket_name>/data/SharePoint/tablename_raw/. CloudTrail captures the PutObject API calls made and relays them as events to EventBridge.

  1. In the Targets section, you can verify that this EventBridge rule is configured with an AWS Glue workflow as a target.

event bridge target section

Run the ingest AWS Glue job and verify the AWS Glue workflow is triggered successfully

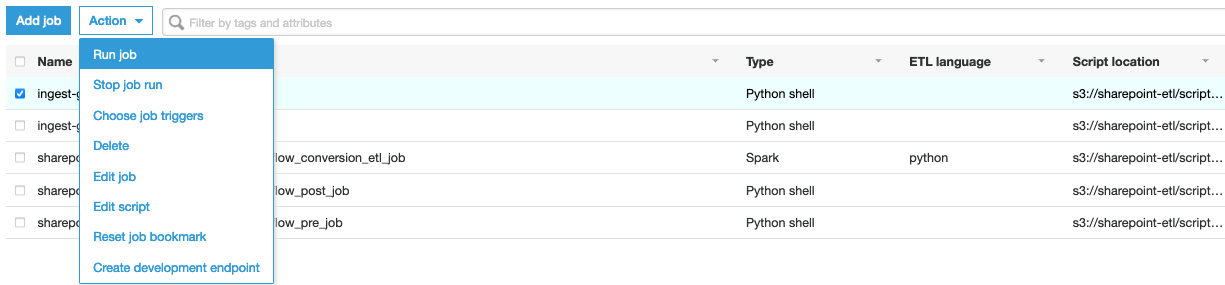
To test the workflow, we run the ingest-glue-job-SharePoint-file job using the following steps:

  1. On the AWS Glue console, select the ingest-glue-job-SharePoint-file job.

glue job

  1. On the Action menu, choose Run job.

glue job action menu

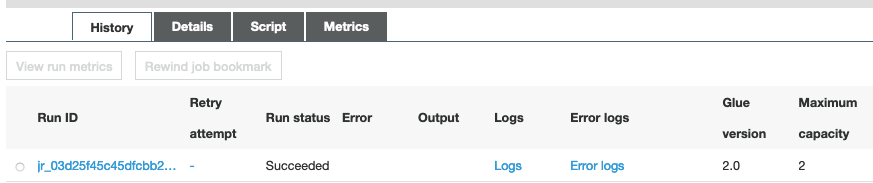
  1. Choose the History tab and wait until the job succeeds.

glue job history tab

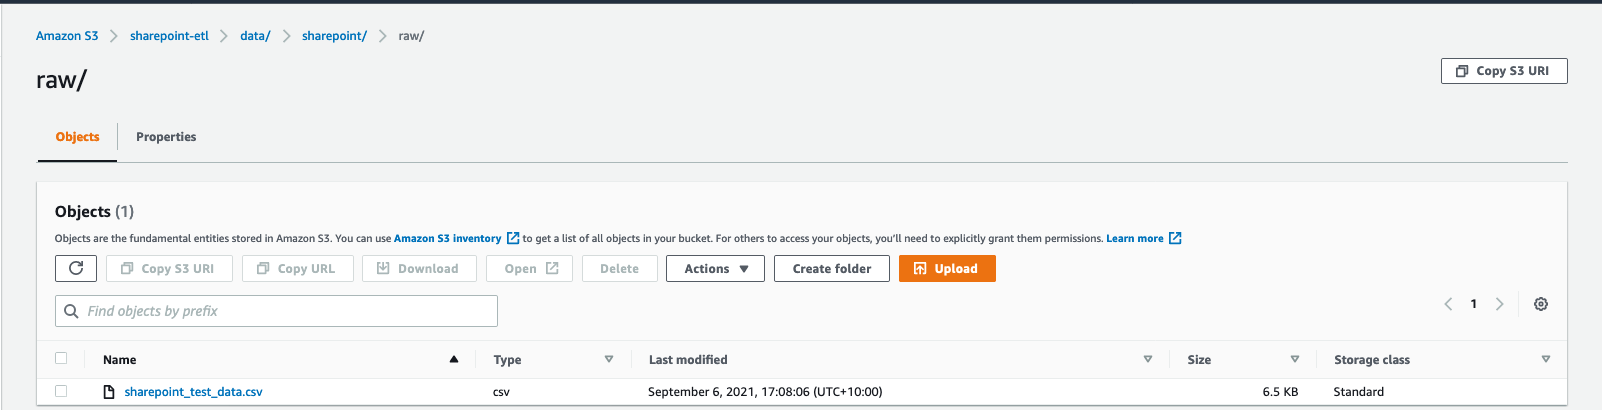
You can now see the CSV files in the raw prefix of your S3 bucket.

csv file s3 location

Now the workflow should be triggered.

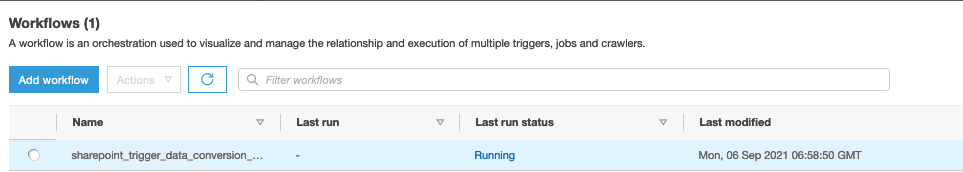
  1. On the AWS Glue console, validate that your workflow is in the RUNNING state.

glue workflow running status

  1. Choose the workflow to view the run details.
  2. On the History tab of the workflow, choose the current or most recent workflow run.
  3. Choose View run details.

glue workflow visual

When the workflow run status changes to Completed, let’s check the converted files in your S3 bucket.

  1. Switch to the Amazon S3 console, and navigate to your bucket.

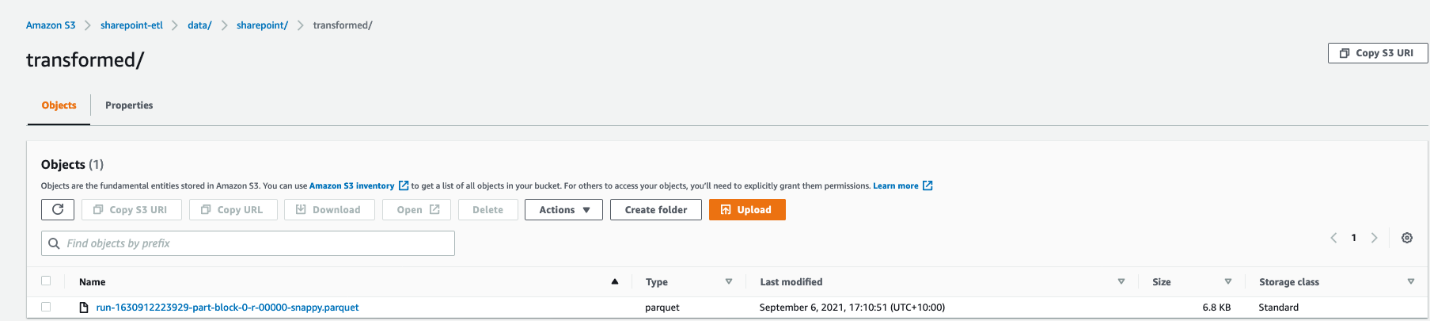
You can see the Parquet files under s3://<bucket_name>/data/SharePoint/tablename_transformed/.

parquet file s3 location

Congratulations! Your workflow ran successfully based on S3 events triggered by uploading files to your bucket. You can verify everything works as expected by running a query against the generated table using Amazon Athena.

Sample wine dataset

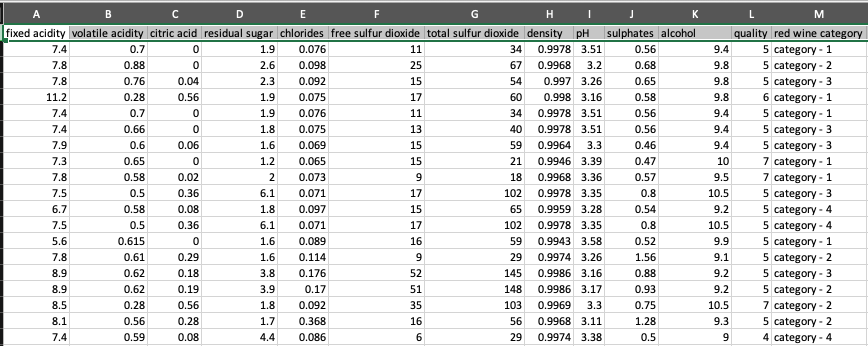
Let’s analyze a sample red wine dataset. The following screenshot shows a SharePoint list that contains various readings that relate to the characteristics of the wine and an associated wine category. This is populated by various wine tasters from multiple countries.

redwine dataset

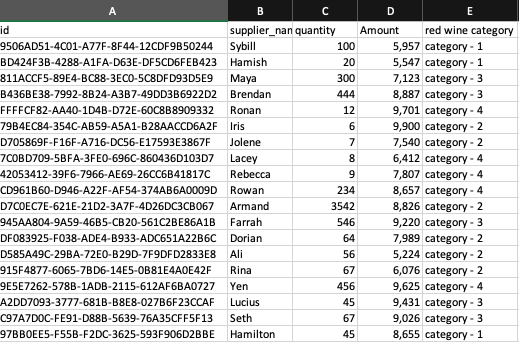
The following screenshot shows a supplier dataset from the data lake with wine categories ordered per supplier.

supplier dataset

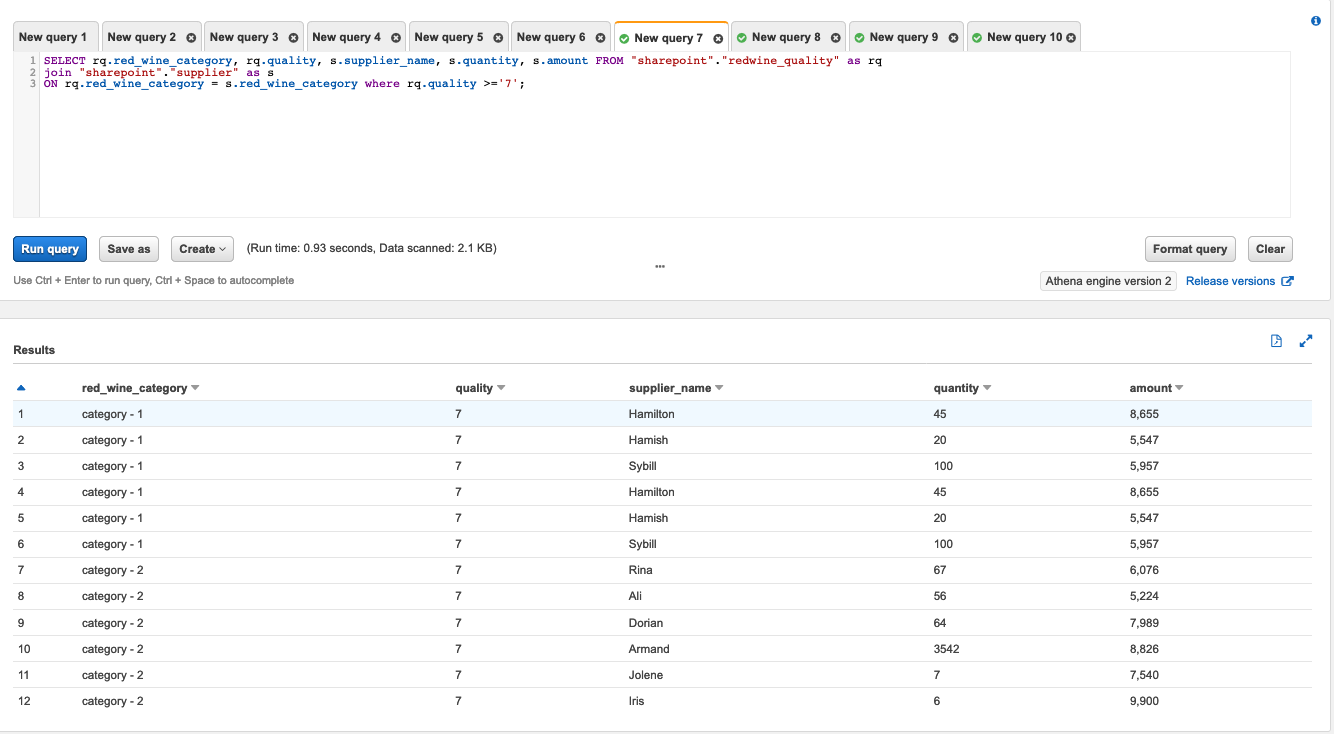
We process the red wine dataset using this solution and use Athena to query the red wine data and supplier data where wine quality is greater than or equal to 7.

athena query and results

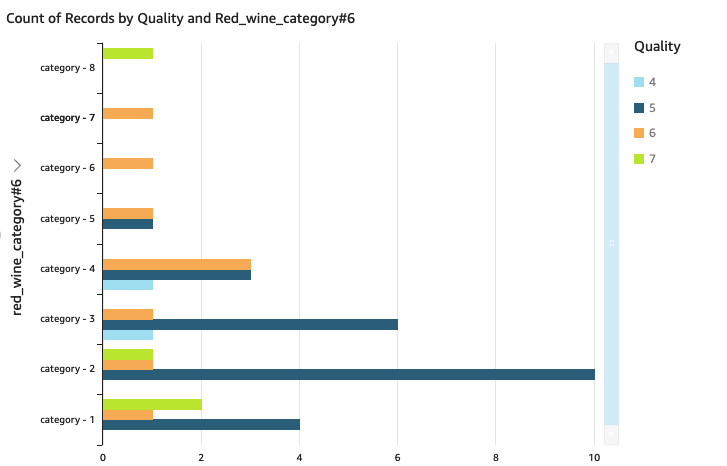
We can visualize the processed dataset using QuickSight.

Clean up

To avoid incurring unnecessary charges, you can use the AWS CloudFormation console to delete the stack that you deployed. This removes all the resources you created when deploying the solution.

Conclusion

Event-driven architectures provide access to near-real-time information and help you make business decisions on fresh data. In this post, we demonstrated how to ingest and process SharePoint data using AWS serverless services like AWS Glue and EventBridge. We saw how to configure a rule in EventBridge to forward events to AWS Glue. You can use this pattern for your analytical use cases, such as joining SharePoint data with other data in your lake to generate insights, or auditing SharePoint data and compliance requirements.


About the Author

Venkata Sistla is a Big Data & Analytics Consultant on the AWS Professional Services team. He specializes in building data processing capabilities and helping customers remove constraints that prevent them from leveraging their data to develop business insights.

Creating static custom domain endpoints with Amazon MQ for RabbitMQ

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/creating-static-custom-domain-endpoints-with-amazon-mq-for-rabbitmq/

This post is written by Nate Bachmeier, Senior Solutions Architect, Wallace Printz, Senior Solutions Architect, Christian Mueller, Principal Solutions Architect.

Many cloud-native application architectures take advantage of the point-to-point and publish-subscribe, or “pub-sub”, model of message-based communication between application components. Not only is this architecture generally more resilient to failure because of the loose coupling and because message processing failures can be retried, it is also more efficient because individual application components can independently scale up or down to maintain message processing SLAs, compared to monolithic application architectures.

Synchronous (REST-based) systems are tightly coupled. A problem in a synchronous downstream dependency has immediate impact on the upstream callers. Retries from upstream callers can fan out and amplify problems.

For applications requiring messaging protocols including JMS, NMS, AMQP, STOMP, MQTT, and WebSocket, Amazon provides Amazon MQ. This is a managed message broker service for Apache ActiveMQ and RabbitMQ that makes it easier to set up and operate message brokers in the cloud.

Amazon MQ provides two managed broker deployment connection options: public brokers and private brokers. Public brokers receive internet-accessible IP addresses while private brokers receive only private IP addresses from the corresponding CIDR range in their VPC subnet. In some cases, for security purposes, customers may prefer to place brokers in a private subnet, but also allow access to the brokers through a persistent public endpoint, such as a subdomain of their corporate domain like ‘mq.example.com’.

This blog explains how to provision private Amazon MQ brokers behind a secure public load balancer endpoint using an example subdomain.

AmazonMQ also supports ActiveMQ – to learn more, read Creating static custom domain endpoints with Amazon MQ to simplify broker modification and scaling.

Overview

There are several reasons one might want to deploy this architecture beyond the security aspects. First, human-readable URLs are easier for people to parse when reviewing operations and troubleshooting, such as deploying updates to ‘mq-dev.example.com’ before ‘mq-prod.example.com’. Additionally, maintaining static URLs for your brokers helps reduce the necessity of modifying client code when performing maintenance on the brokers.

The following diagram shows the solutions architecture. This blog post assumes some familiarity with AWS networking fundamentals, such as VPCs, subnets, load balancers, and Amazon Route 53. For additional information on these topics, see the Elastic Load Balancing documentation.

Reference architecture

  1. The client service tries to connect with a RabbitMQ connection string to the domain endpoint setup in Route 53.
  2. The client looks up the domain name from Route 53, which returns the IP address of the Network Load Balancer (NLB).
  3. The client creates a Transport Layer Security (TLS) connection to the NLB with a secure socket layer (SSL) certificate provided from AWS Certificate Manager (ACM).
  4. The NLB chooses a healthy endpoint from the target group and creates a separate SSL connection. This provides secure, end-to-end SSL encrypted messaging between client and brokers.

To build this architecture, you build the network segmentation first, then add the Amazon MQ brokers, and finally the network routing. You need a VPC, one private subnet per Availability Zone, and one public subnet for your bastion host (if desired).

This demonstration VPC uses the 10.0.0.0/16 CIDR range. Additionally, you must create a custom security group for your brokers. You must set up this security group to allow traffic from your Network Load Balancer to the RabbitMQ brokers.

This example does not use this VPC for other workloads so it allows all incoming traffic that originates within the VPC (which includes the NLB) through to the brokers on the AMQP port of 5671 and the web console port of 443.

Inbound rules

Adding the Amazon MQ brokers

With the network segmentation set up, add the Amazon MQ brokers:

  1. Choose Create brokers on the Active Amazon MQ home page.
  2. Toggle the radio button next to RabbitMQ and choose Next.
  3. Choose a deployment mode of either single-instance broker (for development environments), or cluster deployment (for production environments).
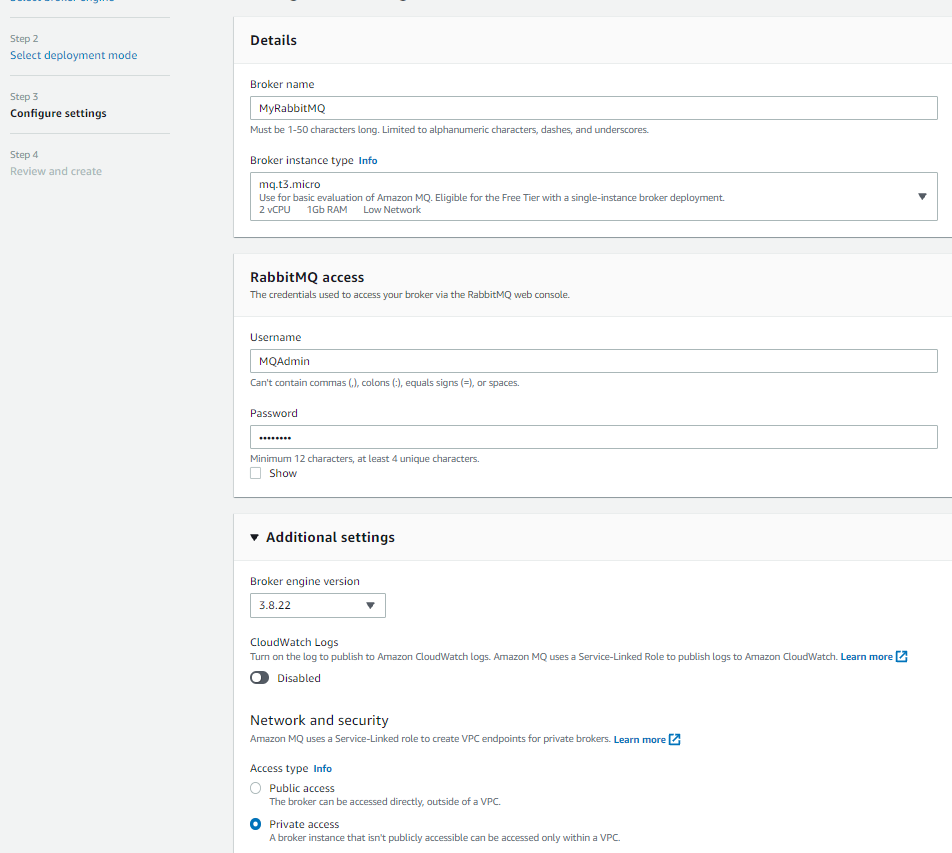
  4. In Configure settings, specify the broker name and instance type.
  5. Confirm that the broker engine version is 3.8.22 or higher and set Access type to Private access.
    Configure settings page
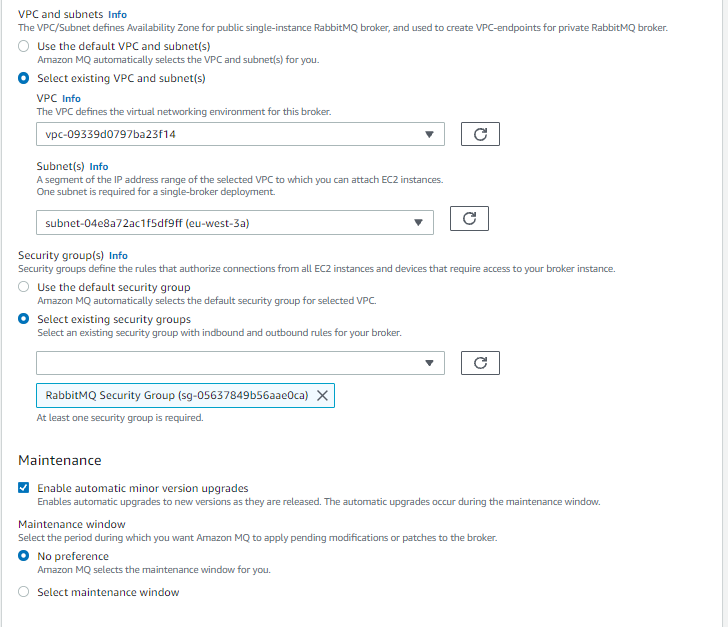
  6. Specify the VPC, private subnets, and security groups before choosing Next.
    Additional settings

Finding the broker’s IP address

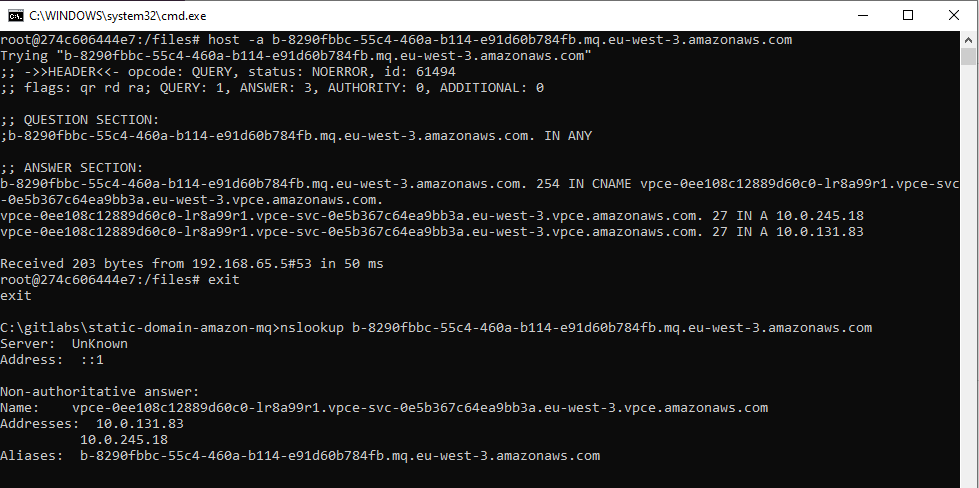
Before configuring the NLB’s target groups, you must look up the broker’s IP address. Unlike Amazon MQ for Apache ActiveMQ, RabbitMQ does not show its private IP addresses, though you can reliably find its VPC endpoints using DNS. Amazon MQ creates one VPC endpoint in each subnet with a static address that won’t change until you delete the broker.

  1. Navigate to the broker’s details page and scroll to the Connections panel.
  2. Find the endpoint’s fully qualified domain name. It is formatted like broker-id.mq.region.amazonaws.com.
  3. Open a command terminal on your local workstation.
  4. Retrieve the ‘A’ record values using the host (Linux) or nslookup (Windows) command.
  5. Record these values for the NLB configuration steps later.
    Terminal results

Configure the load balancer’s target group

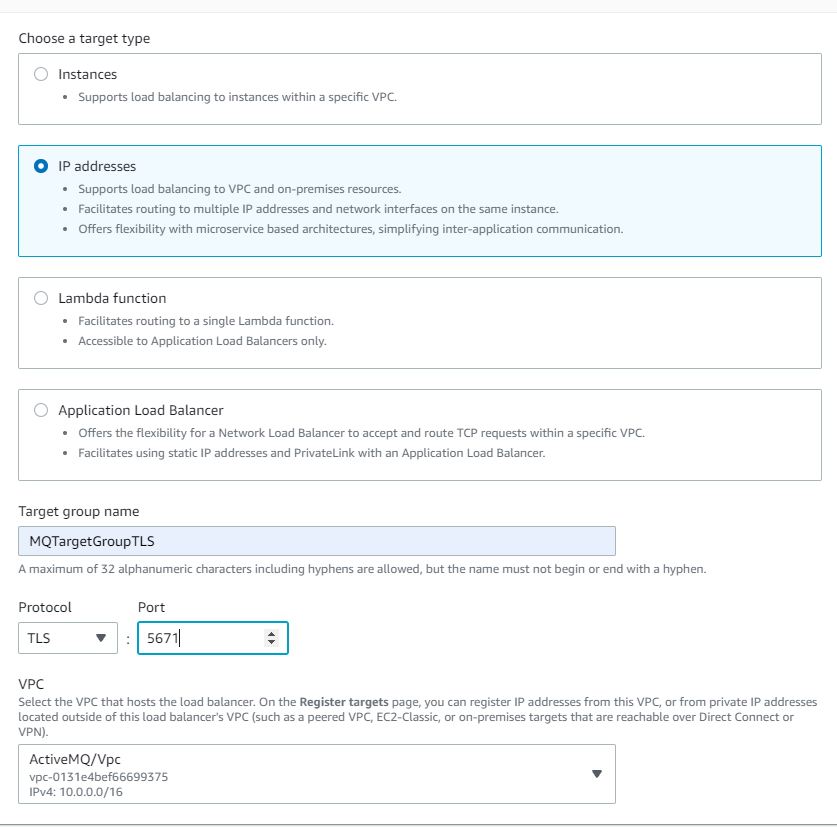
The next step in the build process is to configure the load balancer’s target group. You use the private IP addresses of the brokers as targets for the NLB. Create a Target Group, select the target type as IP, and make sure to choose the TLS protocol and for each required port, as well as the VPC your brokers reside in.

Choose a target type

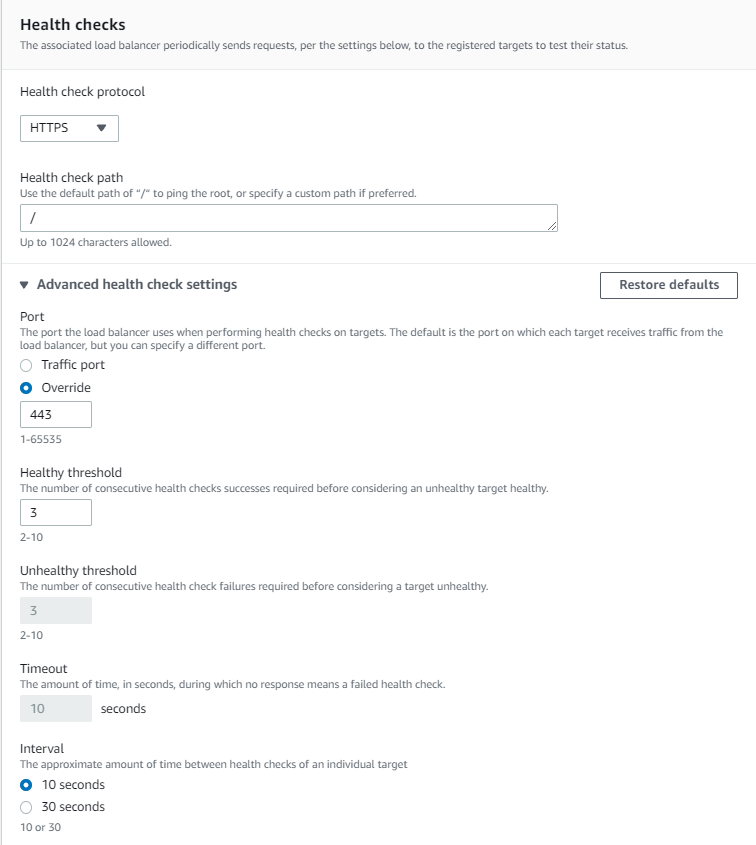
It is important to configure the health check settings so traffic is only routed to active brokers. Select the TCP protocol and override the health check port to 443 Rabbit MQ’s console port. Also, configure the healthy threshold to 2 with a 10-second check interval so the NLB detects faulty hosts within 20 seconds.

Be sure not to use RabbitMQ’s AMQP port as the target group health check port. The NLB may not be able to recognize the host as healthy on that port. It is better to use the broker’s web console port.

Health checks

Add the VPC endpoint addresses as NLB targets. The NLB routes traffic across the endpoints and provides networking reliability if an AZ is offline. Finally, configure the health checks to use the web console (TCP port 443).

Specify IPs and ports

Creating a Network Load Balancer

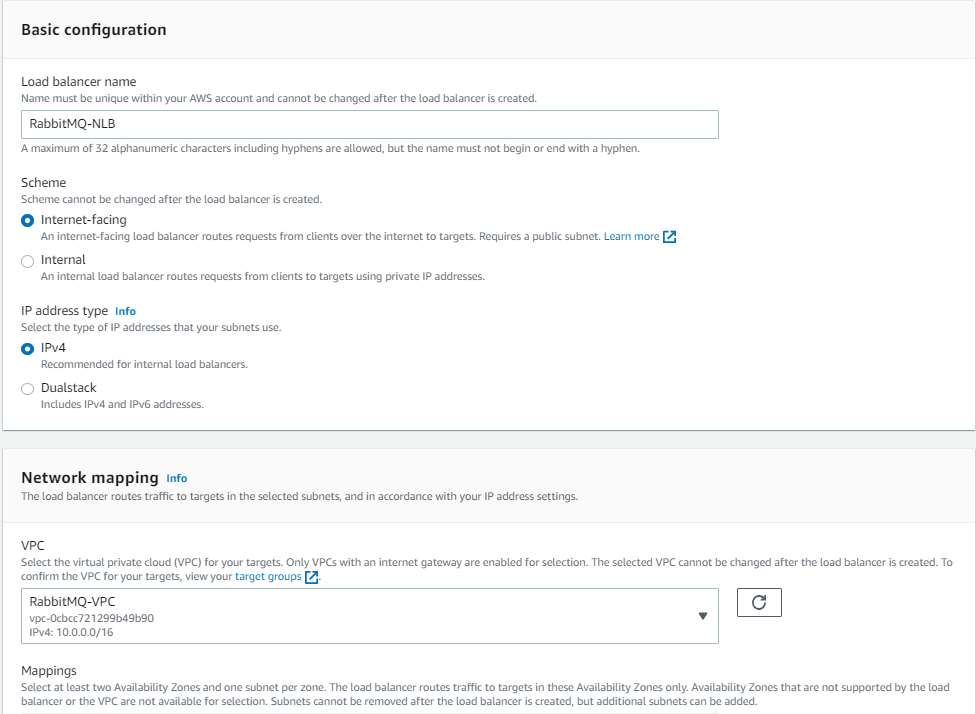
Next, you create a Network Load Balancer. This is an internet-facing load balancer with TLS listeners on port 5671 (AMQP), routing traffic to the brokers’ VPC and private subnets. You select the target group you created, selecting TLS for the connection between the NLB and the brokers. To allow clients to connect to the NLB securely, select an ACM certificate for the subdomain registered in Route 53 (for example ‘mq.example.com’).

To learn about ACM certificate provisioning, read more about the process here. Make sure that the ACM certificate is provisioned in the same Region as the NLB or the certificate is not shown in the dropdown menu.

Basic configuration page

Optionally configure IP filtering

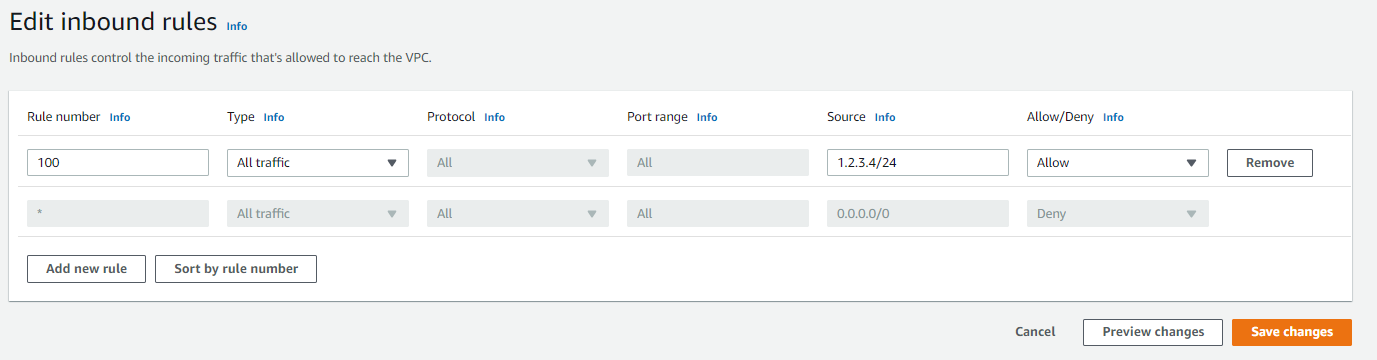
The NLB is globally accessible and this may be overly permissive for some workloads. You can restrict incoming traffic to specific IP ranges on the NLB’s public subnet by using network access control list (NACL) configuration:

  1. Navigate to the AWS Management Console to the VPC service and choose Subnets.
  2. Select your public subnet and then switch to the Network ACL tab.
  3. Select the link to the associated network ACL (e.g., acl-0d6fxxxxxxxx) details.
  4. Activate this item and choose Edit inbound rules in the Action menu.
  5. Specify the desired IP range and then choose Save changes.

Edit inbound rules

Configuring Route 53

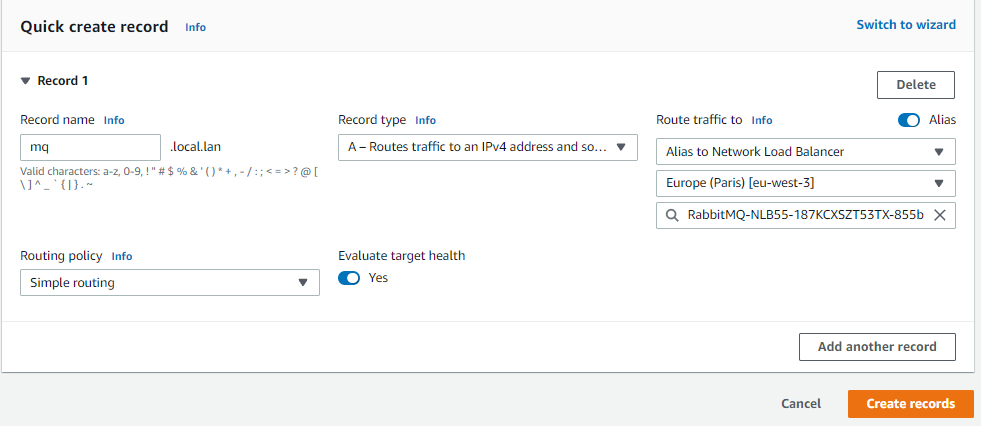
Finally, configure Route 53 to serve traffic at the subdomain of your choice to the NLB:

  1. Go to the Route 53 hosted zone and create a new subdomain record set, such as mq.example.com, that matches the ACM certificate that you previously created.
  2. In the “type” field, select “A – IPv4 address”, then select “Yes” for alias. This allows you to select the NLB as the alias target.
  3. Select from the alias target menu the NLB you just created and save the record set.

Quick create record

Now callers can use the friendly name in the RabbitMQ connection string. This capability improves the developer experience and reduces operational cost when rebuilding the cluster. Since you added multiple VPC endpoints (one per subnet) into the NLB’s target group, the solution has Multi-AZ redundancy.

Testing with a RabbitMQ client process

The entire process can be tested using any RabbitMQ client process. One approach is to launch the official Docker image and connect with the native client. The service documentation also provides sample code for authenticating, publishing, and subscribing to RabbitMQ channels.

To log in to the broker’s RabbitMQ web console, there are three options. Due to the security group rules, only traffic originating from inside the VPC is allowed to the brokers:

  1. Use a VPN connection from your corporate network to the VPC. Many customers use this option but for rapid testing, there is a simpler and more cost-effective method.
  2. Connect to the brokers’ web console through your Route 53 subdomain, which requires creating a separate web console port listener (443) on the existing NLB and creating a separate TLS target group for the brokers.
  3. Use a bastion host to proxy traffic to the web console.

RabbitMQ

Conclusion

In this post, you build a highly available Amazon MQ broker in a private subnet. You layer security by placing the brokers behind a highly scalable Network Load Balancer. You configure routing from a single custom subdomain URL to multiple brokers with a built-in health check.

For more serverless learning resources, visit Serverless Land.

Implementing header-based API Gateway versioning with Amazon CloudFront

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/implementing-header-based-api-gateway-versioning-with-amazon-cloudfront/

This post is written by Amir Khairalomoum, Sr. Solutions Architect.

In this blog post, I show you how to use Lambda@Edge feature of Amazon CloudFront to implement a header-based API versioning solution for Amazon API Gateway.

Amazon API Gateway is a fully managed service that makes it easier for developers to create, publish, maintain, monitor, and secure APIs at any scale. Amazon CloudFront is a global content delivery network (CDN) service built for high-speed, low-latency performance, security, and developer ease-of-use. Lambda@Edge is a feature of Amazon CloudFront, a compute service that lets you run functions that customize the content that CloudFront delivers.

The example uses the AWS SAM CLI to build, deploy, and test the solution on AWS. The AWS Serverless Application Model (AWS SAM) is an open-source framework that you can use to build serverless applications on AWS. The AWS SAM CLI lets you locally build, test, and debug your applications defined by AWS SAM templates. You can also use the AWS SAM CLI to deploy your applications to AWS, or create secure continuous integration and deployment (CI/CD) pipelines.

After an API becomes publicly available, it is used by customers. As a service evolves, its contract also evolves to reflect new changes and capabilities. It’s safe to evolve a public API by adding new features but it’s not safe to change or remove existing features.

Any breaking changes may impact consumer’s applications and break them at runtime. API versioning is important to avoid breaking backward compatibility and breaking a contract. You need a clear strategy for API versioning to help consumers adopt them.

Versioning APIs

Two of the most commonly used API versioning strategies are URI versioning and header-based versioning.

URI versioning

This strategy is the most straightforward and the most commonly used approach. In this type of versioning, versions are explicitly defined as part of API URIs. These example URLs show how domain name, path, or query string parameters can be used to specify a version:

https://api.example.com/v1/myservice
https://apiv1.example.com/myservice
https://api.example.com/myservice?v=1

To deploy an API in API Gateway, the deployment is associated with a stage. A stage is a logical reference to a lifecycle state of your API (for example, dev, prod, beta, v2). As your API evolves, you can continue to deploy it to different stages as different versions of the API.

Header-based versioning

This strategy is another commonly used versioning approach. It uses HTTP headers to specify the desired version. It uses the “Accept” header for content negotiation or uses a custom header (for example, “APIVER” to indicate a version):

Accept:application/vnd.example.v1+json
APIVER:v1

This approach allows you to preserve URIs between versions. As a result, you have a cleaner and more understandable set of URLs. It is also easier to add versioning after design. However, you may need to deal with complexity of returning different versions of your resources.

Overview of solution

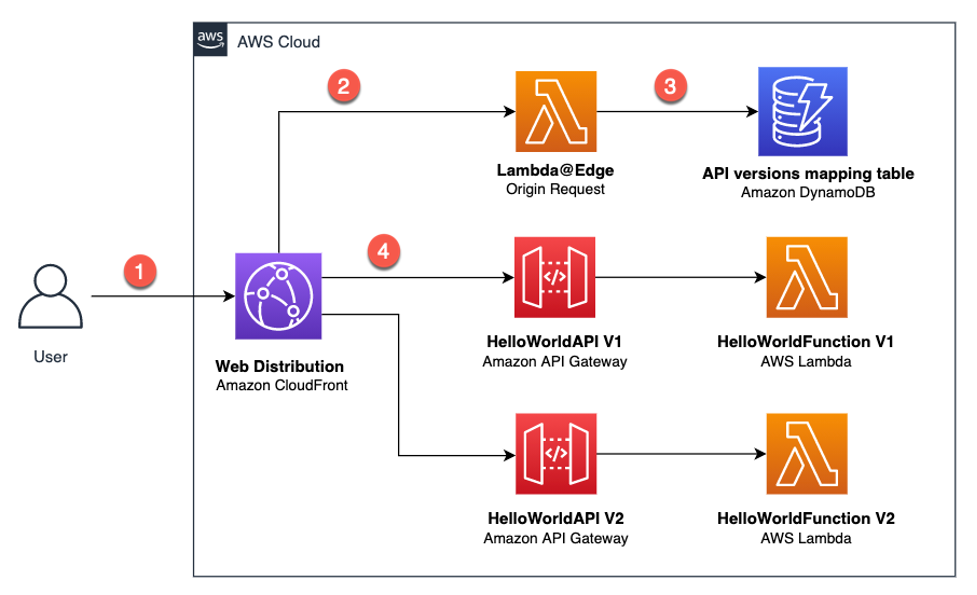
The target architecture for the solution uses Lambda@Edge. It dynamically routes a request to the relevant API version, based on the provided header:

Architecture overview

Architecture overview

In this architecture:

  1. The user sends a request with a relevant header, which can be either “Accept” or another custom header.
  2. This request reaches the CloudFront distribution and triggers the Lambda@Edge Origin Request.
  3. The Lambda@Edge function uses the provided header value and fetches data from an Amazon DynamoDB table. This table contains mappings for API versions. The function then modifies the Origin and the Host header of the request and returns it back to CloudFront.
  4. CloudFront sends the request to the relevant Amazon API Gateway URL.

In the next sections, I walk you through setting up the development environment and deploying and testing this solution.

Setting up the development environment

To deploy this solution on AWS, you use the AWS Cloud9 development environment.

  1. Go to the AWS Cloud9 web console. In the Region dropdown, make sure you’re using N. Virginia (us-east-1) Region.
  2. Select Create environment.
  3. On Step 1 – Name environment, enter a name for the environment, and choose Next step.
  4. On Step 2 – Configure settings, keep the existing environment settings.

    Console view of configuration settings

    Console view of configuration settings

  5. Choose Next step. Choose Create environment.

Deploying the solution

Now that the development environment is ready, you can proceed with the solution deployment. In this section, you download, build, and deploy a sample serverless application for the solution using AWS SAM.

Download the sample serverless application

The solution sample code is available on GitHub. Clone the repository and download the sample source code to your Cloud9 IDE environment by running the following command in the Cloud9 terminal window:

git clone https://github.com/aws-samples/amazon-api-gateway-header-based-versioning.git ./api-gateway-header-based-versioning

This sample includes:

  • template.yaml: Contains the AWS SAM template that defines your application’s AWS resources.
  • hello-world/: Contains the Lambda handler logic behind the API Gateway endpoints to return the hello world message.
  • edge-origin-request/: Contains the Lambda@Edge handler logic to query the API version mapping and modify the Origin and the Host header of the request.
  • init-db/: Contains the Lambda handler logic for a custom resource to populate sample DynamoDB table

Build your application

Run the following commands in order to first, change into the project directory, where the template.yaml file for the sample application is located then build your application:

cd ~/environment/api-gateway-header-based-versioning/
sam build

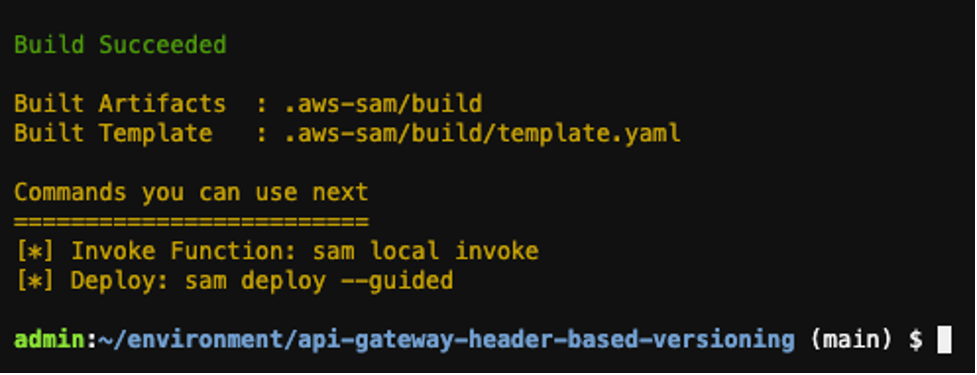
Output:

Build output

Build output

Deploy your application

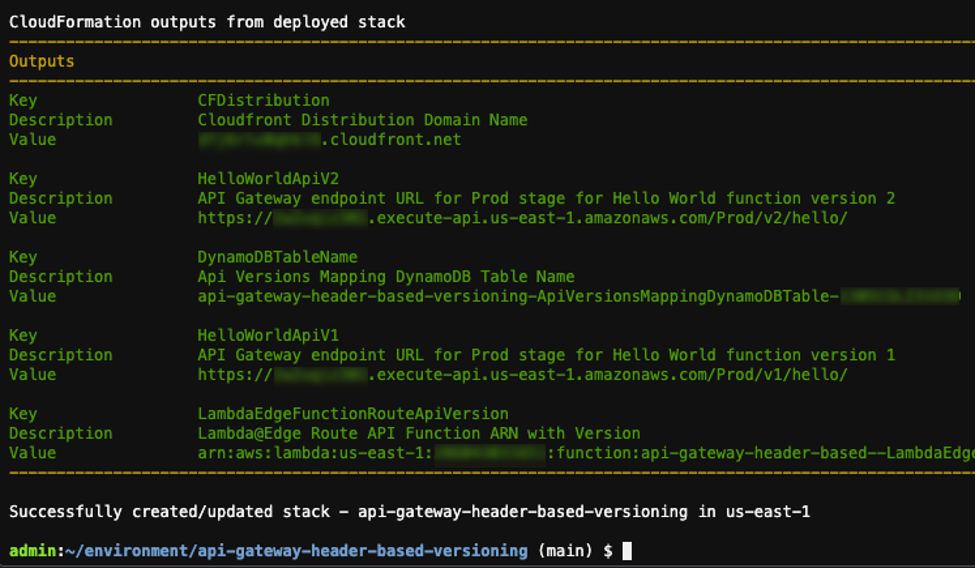
Run the following command to deploy the application in guided mode for the first time then follow the on-screen prompts:

sam deploy --guided

Output:

Deploy output

Deploy output

The output shows the deployment of the AWS CloudFormation stack.

Testing the solution

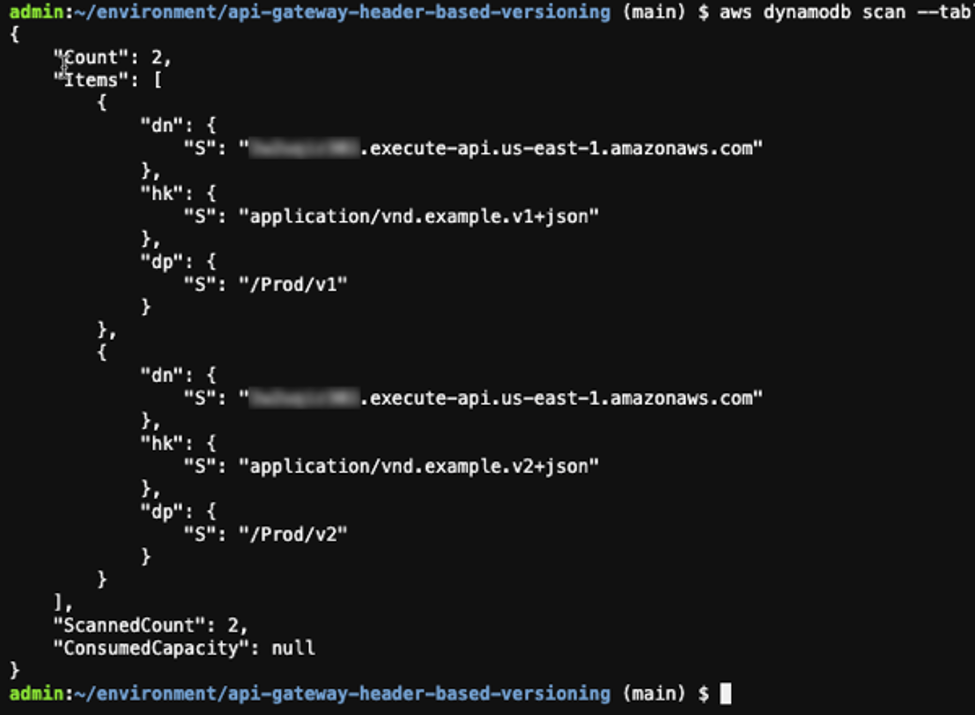
This application implements all required components for the solution. It consists of two Amazon API Gateway endpoints backed by AWS Lambda functions. The deployment process also initializes the API Version Mapping DynamoDB table with the values provided earlier in the deployment process.

Run the following commands to see the created mappings:

STACK_NAME=$(grep stack_name ~/environment/api-gateway-header-based-versioning/samconfig.toml | awk -F\= '{gsub(/"/, "", $2); gsub(/ /, "", $2); print $2}')

DDB_TBL_NAME=$(aws cloudformation describe-stacks --region us-east-1 --stack-name $STACK_NAME --query 'Stacks[0].Outputs[?OutputKey==`DynamoDBTableName`].OutputValue' --output text) && echo $DDB_TBL_NAME

aws dynamodb scan --table-name $DDB_TBL_NAME

Output:

Table scan results

Table scan results

When a user sends a GET request to CloudFront, it routes the request to the relevant API Gateway endpoint version according to the provided header value. The Lambda function behind that API Gateway endpoint is invoked and returns a “hello world” message.

To send a request to the CloudFront distribution, which is created as part of the deployment process, first get its domain name from the deployed AWS CloudFormation stack:

CF_DISTRIBUTION=$(aws cloudformation describe-stacks --region us-east-1 --stack-name $STACK_NAME --query 'Stacks[0].Outputs[?OutputKey==`CFDistribution`].OutputValue' --output text) && echo $CF_DISTRIBUTION

Output:

Domain name results

Domain name results

You can now send a GET request along with the relevant header you specified during the deployment process to the CloudFront to test the application.

Run the following command to test the application for API version one. Note that if you entered a different value other than the default value provided during the deployment process, change the --header parameter to match your inputs:

curl -i -o - --silent -X GET "https://${CF_DISTRIBUTION}/hello" --header "Accept:application/vnd.example.v1+json" && echo

Output:

Curl results

Curl results

The response shows that CloudFront successfully routed the request to the API Gateway v1 endpoint as defined in the mapping Amazon DynamoDB table. API Gateway v1 endpoint received the request. The Lambda function behind the API Gateway v1 was invoked and returned a “hello world” message.

Now you can change the header value to v2 and run the command again this time to test the API version two:

curl -i -o - --silent -X GET "https://${CF_DISTRIBUTION}/hello" --header "Accept:application/vnd.example.v2+json" && echo

Output:

Curl results after header change

Curl results after header change

The response shows that CloudFront routed the request to the API Gateway v2 endpoint as defined in the mapping DynamoDB table. API Gateway v2 endpoint received the request. The Lambda function behind the API Gateway v2 was invoked and returned a “hello world” message.

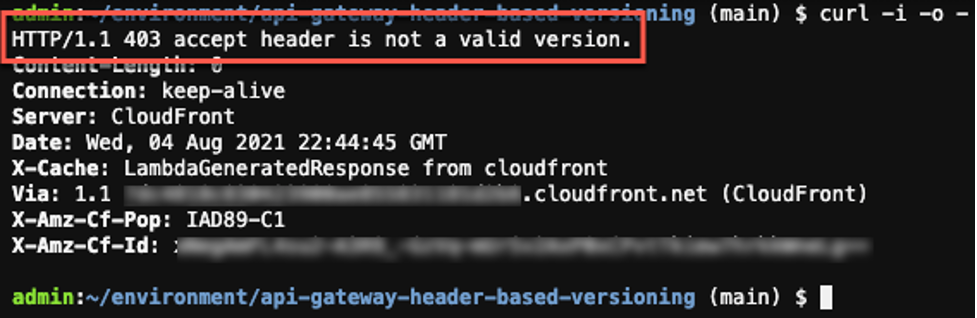
This solution requires valid a header value on each individual request, so the application checks and raises an error if the header is missing or the header value is not valid.

You can remove the header parameter and run the command to test this scenario:

curl -i -o - --silent -X GET "https://${CF_DISTRIBUTION}/hello" && echo

Output:

No header causes a 403 error

No header causes a 403 error

The response shows that Lambda@Edge validated the request and raised an error to inform us that the request did not have a valid header.

Mitigating latency

In this solution, Lambda@Edge reads the API version mappings data from the DynamoDB table. Accessing external data at the edge can cause additional latency to the request. In order to mitigate the latency, solution uses following methods:

  1. Cache data in Lambda@Edge memory: As data is unlikely to change across many Lambda@Edge invocations, Lambda@Edge caches API version mappings data in the memory for a certain period of time. It reduces latency by avoiding an external network call for each individual request.
  2. Use Amazon DynamoDB global table: It brings data closer to the CloudFront distribution and reduces external network call latency.

Cleaning up

To clean up the resources provisioned as part of the solution:

  1. Run following command to delete the deployed application:
    sam delete
  2. Go to the AWS Cloud9 web console. Select the environment you created then choose Delete.

Conclusion

Header-based API versioning is a commonly used versioning strategy. This post shows how to use CloudFront to implement a header-based API versioning solution for API Gateway. It uses the AWS SAM CLI to build and deploy a sample serverless application to test the solution in the AWS Cloud.

To learn more about API Gateway, visit the API Gateway developer guide documentation, and for CloudFront, refer to Amazon CloudFront developer guide documentation.

For more serverless learning resources, visit Serverless Land.

Introducing cross-account Amazon ECR access for AWS Lambda

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/introducing-cross-account-amazon-ecr-access-for-aws-lambda/

This post is written by Brian Zambrano, Enterprise Solutions Architect and Indranil Banerjee, Senior Solution Architect.

In December 2020, AWS announced support for packaging AWS Lambda functions using container images. Customers use the container image packaging format for workloads like machine learning inference made possible by the 10 GB container size increase and familiar container tooling.

Many customers use multiple AWS accounts for application development but centralize Amazon Elastic Container Registry (ECR) images to a single account. Until today, a Lambda function had to reside in the same AWS account as the ECR repository that owned the container image. Cross-account ECR access with AWS Lambda functions has been one of the most requested features since launch.

From today, you can now deploy Lambda functions that reference container images from an ECR repository in a different account within the same AWS Region.

Overview

The example demonstrates how to use the cross-account capability using two AWS example accounts:

  1. ECR repository owner: Account ID 111111111111
  2. Lambda function owner: Account ID 222222222222

The high-level process consists of the following steps:

  1. Create an ECR repository using Account 111111111111 that grants Account 222222222222 appropriate permissions to use the image
  2. Build a Lambda-compatible container image and push it to the ECR repository
  3. Deploy a Lambda function in account 222222222222 and reference the container image in the ECR repository from account 111111111111

This example uses the AWS Serverless Application Model (AWS SAM) to create the ECR repository and its repository permissions policy. AWS SAM provides an easier way to manage AWS resources with CloudFormation.

To build the container image and upload it to ECR, use Docker and the AWS Command Line Interface (CLI). To build and deploy a new Lambda function that references the ECR image, use AWS SAM. Find the example code for this project in the GitHub repository.

Create an ECR repository with a cross-account access policy

Using AWS SAM, I create a new ECR repository named cross-account-function in the us-east-1 Region with account 111111111111. In the template.yaml file, RepositoryPolicyText defines the permissions for the ECR Repository. This template grants account 222222222222 access so that a Lambda function in that account can reference images in the ECR repository:

AWSTemplateFormatVersion: '2010-09-09'
Transform: AWS::Serverless-2016-10-31
Description: SAM Template for cross-account-function ECR Repo

Resources:
  HelloWorldRepo:
    Type: AWS::ECR::Repository
    Properties:
      RepositoryName: cross-account-function
      RepositoryPolicyText:
        Version: "2012-10-17"
        Statement:
          - Sid: CrossAccountPermission
            Effect: Allow
            Action:
              - ecr:BatchGetImage
              - ecr:GetDownloadUrlForLayer
            Principal:
              AWS:
                - arn:aws:iam::222222222222:root
          - Sid: LambdaECRImageCrossAccountRetrievalPolicy
            Effect: Allow
            Action:
              - ecr:BatchGetImage
              - ecr:GetDownloadUrlForLayer
            Principal:
              Service: lambda.amazonaws.com
            Condition:
              StringLike:
                aws:sourceArn:
                  - arn:aws:lambda:us-east-1:222222222222:function:*

Outputs:
  ERCRepositoryUri:
    Description: "ECR RepositoryUri which may be referenced by Lambda functions"
    Value: !GetAtt HelloWorldRepo.RepositoryUri

The RepositoryPolicyText has two statements that are required for Lambda functions to work as expected:

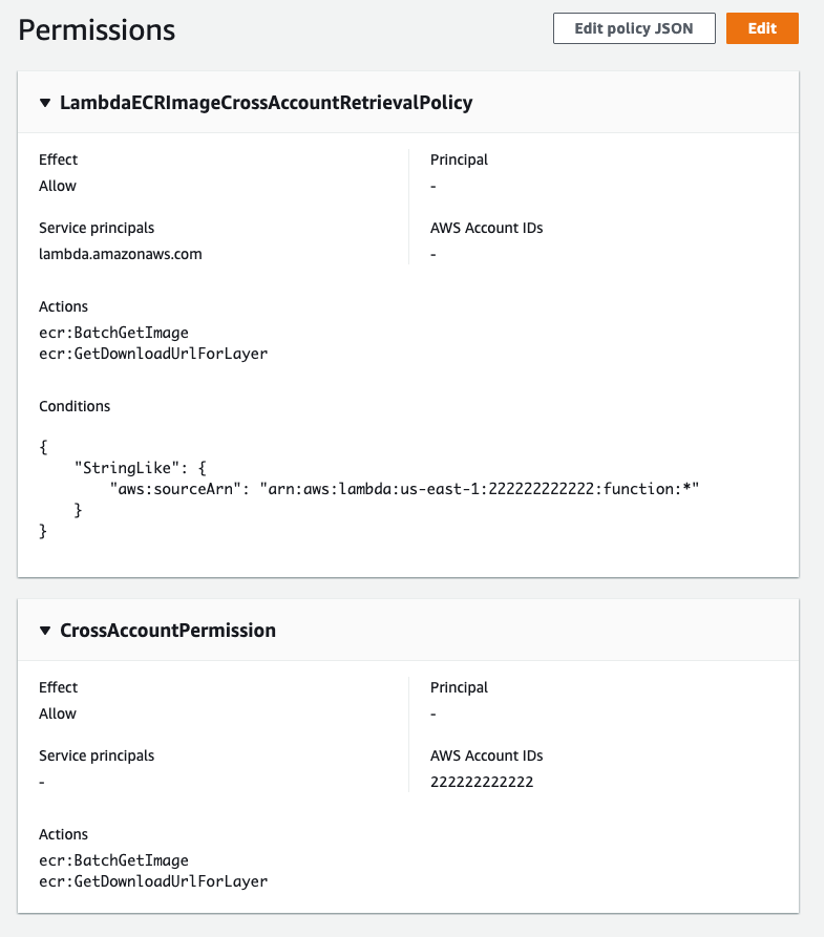
  1. CrossAccountPermission – Allows account 222222222222 to create and update Lambda functions that reference this ECR repository
  2. LambdaECRImageCrossAccountRetrievalPolicy – Lambda eventually marks a function as INACTIVE when not invoked for an extended period. This statement is necessary so that Lambda service in account 222222222222 can pull the image again for optimization and caching.

To deploy this stack, run the following commands:

git clone https://github.com/aws-samples/lambda-cross-account-ecr.git
cd sam-ecr-repo
sam build
AWS SAM build results

AWS SAM build results


sam deploy --guided
SAM deploy results

AWS SAM deploy results

Once AWS SAM deploys the stack, a new ECR repository named cross-account-function exists. The repository has a permissions policy that allows Lambda functions in account 222222222222 to access the container images. You can verify this in the ECR console for this repository:

Permissions displayed in the console

Permissions displayed in the console

You can also extend this policy to enable multiple accounts by adding additional account IDs to the Principal and Condition evaluations lists in the CrossAccountPermission and LambdaECRImageCrossAccountRetrievalPolicy permissions policy. Narrowing the ECR permission policy is a best practice. With this launch, if you are working with multiple accounts in an AWS Organization we recommend enumerating your account IDs in the ECR permissions policy.

Amazon ECR repository policies use a subset of IAM policies to control access to individual ECR repositories. Refer to the ECR repository policies documentation to learn more.

Build a Lambda-compatible container image

Next, you build a container image using Docker and the AWS CLI. For this step, you need Docker, a Dockerfile, and Python code that responds to Lambda invocations.

  1. Use the AWS-maintained Python 3.9 container image as the basis for the Dockerfile:
    FROM public.ecr.aws/lambda/python:3.9
    COPY app.py ${LAMBDA_TASK_ROOT}
    CMD ["app.handler"]

    The code for this example, in app.py, is a Hello World application.

    import json
    def handler(event, context):
        return {
            "statusCode": 200,
            "body": json.dumps({"message": "hello world!"}),
        }
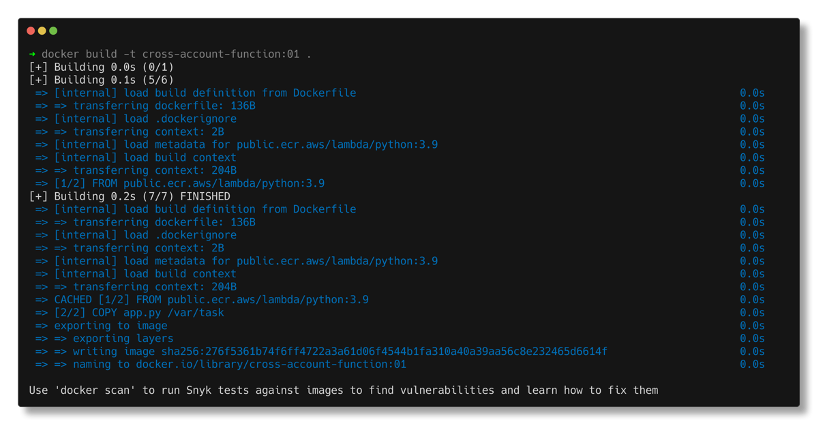
  2. To build and tag the image and push it to ECR using the same name as the repository (cross-account-function) for the image name and 01 as the tag, run:
    $ docker build -t cross-account-function:01 .

    Docker build results

    Docker build results

  3. Tag the image for upload to the ECR. The command parameters vary depending on the account id and Region. If you’re unfamiliar with the tagging steps for ECR, view the exact commands for your repository using the View push commands button from the ECR repository console page:
    $ docker tag cross-account-function:01 111111111111.dkr.ecr.us-east-1.amazonaws.com/cross-account-function:01
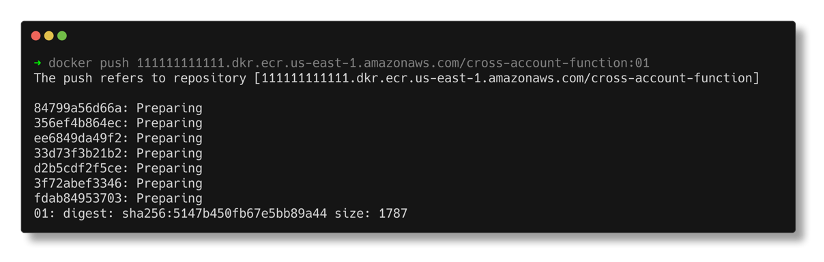
  4. Log in to ECR and push the image:
    $ aws ecr get-login-password --region us-east-1 | docker login --username AWS --password-stdin 111111111111.dkr.ecr.us-east-1.amazonaws.com
    $ docker push 111111111111.dkr.ecr.us-east-1.amazonaws.com/cross-account-function:01

    Docker push results

    Docker push results

Deploying a Lambda Function

The last step is to build and deploy a new Lambda function in account 222222222222. The AWS SAM template below, saved to a file named template.yaml, references the ECR image for the Lambda function’s ImageUri. This template also instructs AWS SAM to create an Amazon API Gateway REST endpoint integrating the Lambda function.

AWSTemplateFormatVersion: '2010-09-09'
Transform: AWS::Serverless-2016-10-31
Description: Sample SAM Template for sam-ecr-cross-account-demo

Globals:
  Function:
    Timeout: 3
Resources:
  HelloWorldFunction:
    Type: AWS::Serverless::Function
    Properties:
      PackageType: Image
      ImageUri: 111111111111.dkr.ecr.us-east-1.amazonaws.com/cross-account-function:01
      Architectures:
        - x86_64
      Events:
        HelloWorld:
          Type: Api
          Properties:
            Path: /hello
            Method: get

Outputs:
  HelloWorldApi:
    Description: "API Gateway endpoint URL for Prod stage for Hello World function"
    Value: !Sub "https://${ServerlessRestApi}.execute-api.${AWS::Region}.amazonaws.com/Prod/hello/"

Use AWS SAM to deploy this template:

cd ../sam-cross-account-lambda
sam build
AWS SAM build results

AWS SAM build results

sam deploy --guided
SAM deploy results

SAM deploy results

Now that the Lambda function is deployed, test using the API Gateway endpoint that AWS SAM created:

Testing the endpoint

Testing the endpoint

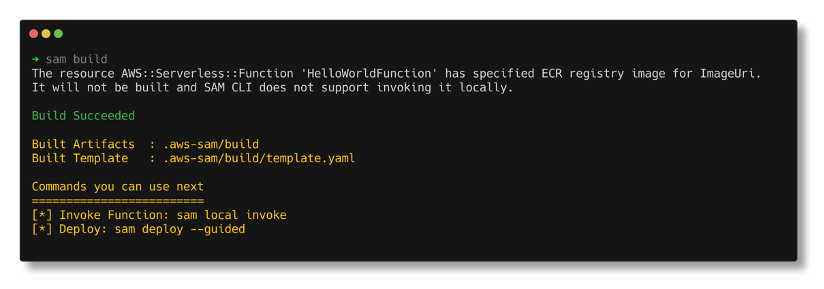
Because it references a container image with the ImageUri parameter in the AWS SAM template, subsequent deployments must use the –resolve-image-repos parameter:

sam deploy --resolve-image-repos

Conclusion

This post demonstrates how to create a Lambda-compatible container image in one account and reference it from a Lambda function in another account. It shows an example of an ECR policy to enable cross-account functionality. It also shows how to use AWS SAM to deploy container-based functions using the ImageUri parameter.

To learn more about serverless and AWS SAM, visit the Sessions with SAM series and find more resources at Serverless Land.

#ServerlessForEveryone

Choosing between storage mechanisms for ML inferencing with AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/choosing-between-storage-mechanisms-for-ml-inferencing-with-aws-lambda/

This post is written by Veda Raman, SA Serverless, Casey Gerena, Sr Lab Engineer, Dan Fox, Principal Serverless SA.

For real-time machine learning inferencing, customers often have several machine learning models trained for specific use-cases. For each inference request, the model must be chosen dynamically based on the input parameters.

This blog post walks through the architecture of hosting multiple machine learning models using AWS Lambda as the compute platform. There is a CDK application that allows you to try these different architectures in your own account. Finally, it then discusses the different storage options for hosting the models and the benefits of each.

Overview

The serverless architecture for inferencing uses AWS Lambda and API Gateway. The machine learning models are stored either in Amazon S3 or Amazon EFS. Alternatively, they are part of the Lambda function deployed as a container image and stored in Amazon ECR.

All three approaches package and deploy the machine learning inference code as Lambda function along with the dependencies as a container image. More information on how to deploy Lambda functions as container images can be found here.

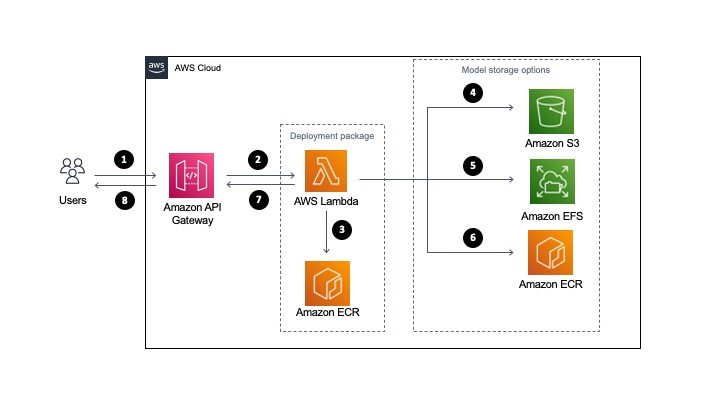
Solution architecture

  1. A user sends a request to Amazon API Gateway requesting a machine learning inference.
  2. API Gateway receives the request and triggers Lambda function with the necessary data.
  3. Lambda loads the container image from Amazon ECR. This container image contains the inference code and business logic to run the machine learning model. However, it does not store the machine learning model (unless using the container hosted option, see step 6).
  4. Model storage option: For S3, when the Lambda function is triggered, it downloads the model files from S3 dynamically and performs the inference.
  5. Model storage option: For EFS, when the Lambda function is triggered, it accesses the models via the local mount path set in the Lambda file system configuration and performs the inference.
  6. Model storage option: If using the container hosted option, you must package the model in Amazon ECR with the application code defined for the Lambda function in step 3. The model runs in the same container as the application code. In this case, choosing the model happens at build-time as opposed to runtime.
  7. Lambda returns the inference prediction to API Gateway and then to the user.

The storage option you choose, either Amazon S3, Amazon EFS, or Amazon ECR via Lambda OCI deployment, to host the models influences the inference latency, cost of the infrastructure and DevOps deployment strategies.

Comparing single and multi-model inference architectures

There are two types of ML inferencing architectures, single model and multi-model. In single model architecture, you have a single ML inference model that performs the inference for all incoming requests. The model is stored either in S3, ECR (via OCI deployment with Lambda), or EFS and is then used by a compute service such as Lambda.

The key characteristic of a single model is that each has its own compute. This means that for every Lambda function there is a single model associated with it. It is a one-to-one relationship.

Multi-model inferencing architecture is where there are multiple models to be deployed and the model to perform the inference should be selected dynamically based on the type of request. So you may have four different models for a single application and you want a Lambda function to choose the appropriate model at invocation time. It is a many-to-one relationship.

Regardless of whether you use single or multi-model, the models must be stored in S3, EFS, or ECR via Lambda OCI deployments.

Should I load a model outside the Lambda handler or inside?

It is a general best practice in Lambda to load models and anything else that may take a longer time to process outside of the Lambda handler. For example, loading a third-party package dependency. This is due to cold start invocation times – for more information on performance, read this blog.

However, if you are running a multi-model inference, you may want to load inside the handler so you can load a model dynamically. This means you could potentially store 100 models in EFS and determine which model to load at the time of invocation of the Lambda function.

In these instances, it makes sense to load the model in the Lambda handler. This can increase the processing time of your function, since you are loading the model at the time of request.

Deploying the solution

The example application is open-sourced. It performs NLP question/answer inferencing using the HuggingFace BERT model using the PyTorch framework (expanding upon previous work found here). The inference code and the PyTorch framework are packaged as a container image and then uploaded to ECR and the Lambda service.

The solution has three stacks to deploy:

  • MlEfsStack – Stores the inference models inside of EFS and loads two models inside the Lambda handler, the model is chosen at invocation time.
  • MlS3Stack – Stores the inference model inside of S3 and loads a single model outside of the Lambda handler.
  • MlOciStack – Stores the inference models inside of the OCI container loads two models outside of the Lambda handler, the model is chosen at invocation time.

To deploy the solution, follow along the README file on GitHub.

Testing the solution

To test the solution, you can either send an inference request through API Gateway or invoke the Lambda function through the CLI. To send a request to the API, run the following command in a terminal (be sure to replace with your API endpoint and Region):

curl --location --request POST 'https://asdf.execute-api.us-east-1.amazonaws.com/develop/' --header 'Content-Type: application/json' --data-raw '{"model_type": "nlp1","question": "When was the car invented?","context": "Cars came into global use during the 20th century, and developed economies depend on them. The year 1886 is regarded as the birth year of the modern car when German inventor Karl Benz patented his Benz Patent-Motorwagen. Cars became widely available in the early 20th century. One of the first cars accessible to the masses was the 1908 Model T, an American car manufactured by the Ford Motor Company. Cars were rapidly adopted in the US, where they replaced animal-drawn carriages and carts, but took much longer to be accepted in Western Europe and other parts of the world."}'

General recommendations for model storage

For single model architectures, you should always load the ML model outside of the Lambda handler for increased performance on subsequent invocations after the initial cold start, this is true regardless of the model storage architecture that is chosen.

For multi-model architectures, if possible, load your model outside of the Lambda handler; however, if you have too many models to load in advance then load them inside of the Lambda handler. This means that a model will be loaded at every invocation of Lambda, increasing the duration of the Lambda function.

Recommendations for model hosting on S3

S3 is a good option if you need a simpler, low-cost storage option to store models. S3 is recommended when you cannot predict your application traffic volume for inference.

Additionally, if you must retrain the model, you can upload the retrained model to the S3 bucket without redeploying the Lambda function.

Recommendations for model hosting on EFS

EFS is a good option if you have a latency-sensitive workload for inference or you are already using EFS in your environment for other machine learning related activities (for example, training or data preparation).

With EFS, you must VPC-enable the Lambda function to mount the EFS filesystem, which requires an additional configuration.

For EFS, it’s recommended that you perform throughput testing with both EFS burst mode and provisioned throughput modes. Depending on inference request traffic volume, if the burst mode is not able to provide the desired performance, you must provision throughput for EFS. See the EFS burst throughput documentation for more information.

Recommendations for container hosted models

This is the simplest approach since all the models are available in the container image uploaded to Lambda. This also has the lowest latency since you are not downloading models from external storage.

However, it requires that all the models are packaged into the container image. If you have too many models that cannot fit into the 10 GB of storage space in the container image, then this is not a viable option.

One drawback of this approach is that anytime a model changes, you must re-package the models with the inference Lambda function code.

This approach is recommended if your models can fit in the 10 GB limit for container images and you are not re-training models frequently.

Cleaning up

To clean up resources created by the CDK templates, run “cdk destroy <StackName>”

Conclusion

Using a serverless architecture for real-time inference can scale your application for any volume of traffic while removing the operational burden of managing your own infrastructure.

In this post, we looked at the serverless architecture that can be used to perform real-time machine learning inference. We then discussed single and multi-model architectures and how to load the models in the Lambda function. We then looked at the different storage mechanisms available to host the machine learning models. We compared S3, EFS, and container hosting for storing models and provided our recommendations of when to use each.

For more learning resources on serverless, visit Serverless Land.

Build workflows for Amazon Forecast with AWS Step Functions

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/build-workflows-for-amazon-forecast-with-aws-step-functions/

This post is written by Péter Molnár, Data Scientist, ML ProServe and Sachin Doshi, Senior Application Architect, ProServe.

This blog builds a full lifecycle workflow for Amazon Forecast to predict household electricity consumption from historic data. Previously, developers used AWS Lambda function to build workflows for Amazon Forecast. You can now use AWS Step Functions with AWS SDK integrations to reduce cost and complexity.

Step Functions recently expanded the number of supported AWS service integrations from 17 to over 200 with AWS API actions from 46 to over 9,000 with AWS SDK service integrations.

Step Functions is a low-code visual workflow service used for workflow automation and service orchestration. Developers use Step Functions with managed services such as artificial intelligence services, Amazon S3, and AWS Glue.

You can create state machines that use AWS SDK Service Integrations with Amazon States Language (ASL), AWS Cloud Development Kit (AWS CDK), AWS Serverless Application Model (AWS SAM), or visually using AWS Step Function Workflow Studio.

To create workflows for AWS AI services like Forecast, you can use Step Functions AWS SDK service integrations. This approach can be simpler because it allows users to build solutions without writing JavaScript or Python code.

Workflow for Amazon Forecast

The solution includes four components:

Solution architecture

  1. IAM role granting Step Functions control over Forecast.
  2. IAM role granting Forecast access to S3 storage locations.
  3. S3 bucket with input data
  4. Define Step Functions state machine and parameters for Forecast.

The repo provides an AWS SAM template to deploy these resources in your AWS account.

Understanding Amazon Forecast

Amazon Forecast is a fully managed service for time series forecasting. Forecast uses machine learning to combine time series data with additional variables to build forecasts.

Using Amazon Forecast involves steps that may take from minutes to hours. Instead of executing each step and waiting for its completion, you use Step Functions to define the steps of the forecasting process.

These are the individual steps of the Step Functions workflow:

Step Functions workflow

  1. Create a dataset: In Forecast, there are three types of datasets, target time series, related time series, and item metadata. The target time series is required and the others provide additional context with certain algorithms.
  2. Import data: This moves the information from S3 into a storage volume where the data is used for training and validation.
  3. Create a dataset group: This is the large box that isolates models and the data they are trained on from each other.
  4. Train a model: Forecast automates this process for you but you can also select algorithms. You can provide your own hyper parameters or use hyperparameter optimization (HPO) to determine the most performant values.
  5. Export back-test results: this creates a detailed table of the model performance.
  6. Deploy a predictor to deploy the model to use it to generate a forecast.
  7. Export forecast to create future predictions.

For more details, read the documentation of the Forecast APIs.

Example dataset

This example uses the individual household electric power consumption dataset. This dataset is available from the UCI Machine Learning Repository. We have aggregated the usage data to hourly intervals.

The dataset has three columns: the timestamp, value, and item ID. These are the minimum required to generate a forecast with Amazon Forecast.

Read more about the data and parameters in https://github.com/aws-samples/amazon-forecast-samples/tree/master/notebooks/basic/Tutorial.

Step Functions AWS SDK integrations

The AWS SDK integrations of Step Functions reduce the need for Lambda functions that call the Forecast APIs. You can call any AWS SDK-compatible service directly from the ASL. Use the following syntax in the resource field of a Step Functions task:

arn:aws:states:::aws-sdk:serviceName:apiAction.[serviceIntegrationPattern]

The following example compares using Step Functions AWS SDK service integrations with calling the boto3 Python method to create a dataset with a corresponding resource in the state machine definition. This is the ASL of a Step Functions state machine:

"States": {
  "Create-Dataset": {
    "Resource": "arn:aws:states:::aws-sdk:forecast:createDataset",
    "Parameters": {
      "DatasetName": "blog_example",
      "DataFrequency": "H",
      "Domain": "CUSTOM",
      "DatasetType": "TARGET_TIME_SERIES",
      "Schema": {
        "Attributes": [
          {
            "AttributeName": "timestamp",
            "AttributeType": "timestamp"
          },
          {
            "AttributeName": "target_value",
            "AttributeType": "float"
          },
          {
            "AttributeName": "item_id",
            "AttributeType": "string"
          }
        ]
      }
    },
    "ResultPath": "$.createDatasetResult",
    "Next": "Import-Data"
  }

The structure is similar to the corresponding boto3 methods. Compare the Python code with the state machine code – it uses the same parameters as calling the Python API:

forecast = boto3.client('forecast')
response = forecast.create_dataset(
             Domain='CUSTOM',
             DatasetType='TARGET_TIME_SERIES',
             DatasetName='blog_example',
             DataFrequency='H', 
             Schema={
               'Attributes': [
                  {
                    'AttributeName': 'timestamp',
                    'AttributeType': 'timestamp'
                  },
                  {
                    'AttributeName': 'target_value',
                    'AttributeType': 'float'
                  },
                  {
                    'AttributeName': 'item_id',
                    'AttributeType': 'string'
                  }
               ]
             }
           )

Handling asynchronous API calls

Several Forecast APIs run asynchronously, such as createDatasetImportJob and createPredictor. This means that your workflow must wait until the import job is completed.

You can use one of two methods in the state machine: create a wait loop, or allow any following task that depends on the completion of the previous task to retry.

In general, it is good practice to allow any task to retry for a few times. For simplicity this example does not include general error handling. Read the blog Handling Errors, Retries, and adding Alerting to Step Function State Machine Executions to learn more about writing robust state machines.

1. State machine wait loop

Wait loop

To wait for an asynchronous task to complete, use the services’ Describe* API methods to get the status of current job. You can implement the wait loop with the native Step Function tasks Choice and Wait.

Here, the task “Check-Data-Import” calls the describeDatasetImportJob API to receive a status value of the running job:

"Check-Data-Import": {
  "Type": "Task",
  "Resource": "arn:aws:states:::aws-sdk:forecast:describeDatasetImportJob",
  "Parameters": {
    "DatasetImportJobArn.$": "$.createDatasetImportJobResult.DatasetImportJobArn"
   },
   "ResultPath": "$.describeDatasetImportJobResult",
   "Next": "Fork-Data-Import"
 },
 "Fork-Data-Import": {
   "Type": "Choice",
   "Choices": [
     {
       "Variable": "$.describeDatasetImportJobResult.Status",
       "StringEquals": "ACTIVE",
       "Next": "Done-Data-Import"
     }
   ],
   "Default": "Wait-Data-Import"
 },
 "Wait-Data-Import": {
   "Type": "Wait",
   "Seconds": 60,
   "Next": "Check-Data-Import"
 },
 "Done-Data-Import": {
   "Type": "Pass",
   "Next": "Create-Predictor"
 },

2. Fail and retry

Alternatively, use the Retry parameter to specify how to repeat the API call in case of an error. This example shows how the attempt to create the forecast is repeated if the resource that it depends on is not created. In this case, the preceding task of creating the predictor.

The time between retries is set to 180 seconds and the number of retries must not exceed 100. This means that the workflow waits 3 minutes before trying again. The longest time to wait for the ML training is five hours.

With the BackoffRate set to 1, the wait interval of 3 minutes remains constant. Value greater that 1 may reduce the number of retries but may also add increased wait time for training jobs that run for several hours:

"Create-Forecast": {
  "Type": "Task",
  "Resource": "arn:aws:states:::aws-sdk:forecast:createForecast",
  "Parameters": {
    "ForecastName.$": "States.Format('{}_forecast', $.ProjectName)",
    "PredictorArn.$": "$.createPredictorResult.PredictorArn"
   },
   "ResultPath": "$.createForecastResult",
   "Retry": [
     {
       "ErrorEquals": ["Forecast.ResourceInUseException"],
       "IntervalSeconds": 180,
       "BackoffRate": 1.0,
       "MaxAttempts": 100
     }
   ],
   "Next": "Forecast-Export"
 },

Deploying the workflow

The AWS Serverless Application Model Command Line Interface (AWS SAM CLI) is an extension of the AWS CLI that adds functionality for building and testing serverless applications. Follow the instructions to install the AWS SAM CLI.

To build and deploy the application:

  1. Clone the GitHub repo:
    git clone https://github.com/aws-samples/aws-stepfunctions-examples/tree/main/sam/demo-forecast-service-integration
  2. Change directory to cloned repo.
    cd demo-forecast-service-integration
  3. Enable execute permissions for the deployment script
    chmod 700 ./bootstrap_deployment_script.sh
  4. Execute the script with a stack name of your choosing as parameter.
    ./bootstrap_deployment_script.sh <Here goes your stack name>

The script builds the AWS SAM template and deploys the stack under the given name. The AWS SAM template creates the underlying resources like S3 bucket, IAM policies, and Step Functions workflow. The script also copies the data file used for training to the newly created S3 bucket.

Running the workflow

After the AWS SAM Forecast workflow application is deployed, run the workflow to train a forecast predictor for the energy consumption:

  1. Navigate to the AWS Step Functions console.
  2. Select the state machine named “ForecastWorkflowStateMachine-*” and choose New execution.
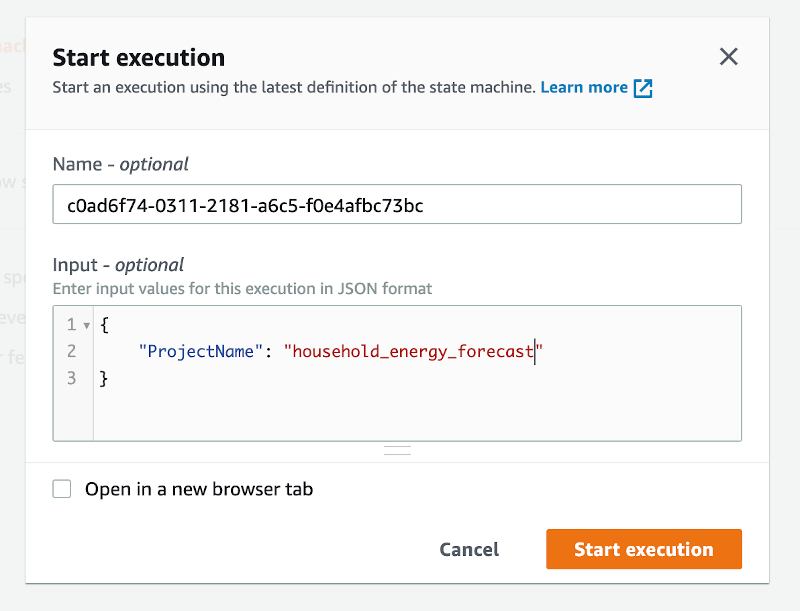
  3. Define the “ProjectName” parameter in form of a JSON structure. The name for the Forecast Dataset group is “household_energy_forecast”.
    Start execution
  4. Choose Start execution.

Viewing resources in the Amazon Forecast console

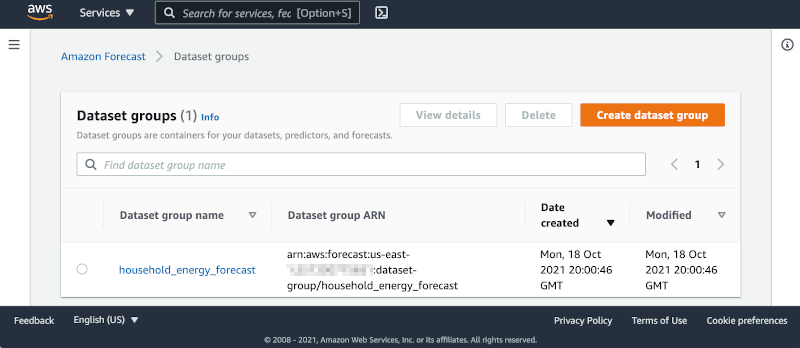
Navigate to the Amazon Forecast console and select the data set group “household_energy_forecast”. You can see the details of the Forecast resource as they are created. The provided state machine executes every step in the workflow and then deletes all resources, leaving the output files in S3.

Amazon Forecast console

You can disable the clean-up process by editing the state machine:

  1. Choose Edit to open the editor.
  2. Find the tasks “Clean-Up” and change the “Next” state from “Delete-Forecast_export” to “SuccessState”.
    "Clean-Up": {
       "Type": "Pass",
       "Next": "SuccessState"
    },
    
  3. Delete all tasks named Delete-*.

Remember to delete the dataset group manually if you bypass the clean-up process of the workflow.

Analyzing Forecast Results

The forecast workflow creates a folder “forecast_results” for all of its output files. In there you find the subfolders “backtestexport” with data produced by Backtest-Export task, and “forecast” with the predicted energy demand forecast produced by the Forecast-Export job.

The “backtestexport” folder contains two tables: “accuracy-metrics-values” with the model performance accuracy metrics, and “forecast-values” with the predicted forecast values of the training set. Read the blog post Amazon Forecast now supports accuracy measurements for individual items for details.

The forecast predictions are stored in the “forecast” folder. The table contains forecasts at three different quantiles: 10%, 50% and 90%.

The data files are partitioned into multiple CSV files. In order to analyze them, first download and merge the files into proper tables. Use the AWS CLI command to download

BUCKET="<your account number>-<your region>-sf-forecast-workflow"
aws s3 cp s3://$BUCKET/forecast_results . –recursive

Alternatively, you may import and analyze the data into Amazon Athena.

Cleaning up

To delete the application that you created, use the AWS SAM CLI.

sam delete --stack-name <Here goes your stack name>

Also delete the data files in the S3 bucket. If you skipped the clean-up tasks in your workflow, you must delete the dataset group from the Forecast console.

Important things to know

Here are things know, that will help you to use AWS SDK service integration:

  • Call AWS SDK services directly from the ASL in the resource field of a task state. To do this, use the following syntax: arn:aws:states:::aws-sdk:serviceName:apiAction.[serviceIntegrationPattern]
  • Use camelCase for apiAction names in the Resource field, such as “copyObject”, and use PascalCase for parameter names in the Parameters field, such as “CopySource”.
  • Step Functions cannot generate IAM policies for most AWS SDK service integrations. You must add those to the IAM role of the state machine explicitly.

Learn more about this new capability by reading its documentation.

Conclusion

This post shows how to create a Step Functions workflow for Forecast using AWS SDK service integrations, which allows you to use over 200 with AWS API actions. It shows two patterns for handling asynchronous tasks. The first pattern queries the describe-* API repeatedly and the second pattern uses the “Retry” option. This simplifies the development of workflows because in many cases they can replace Lambda functions.

For more serveless learning resources, visit Serverless Land.

Creating AWS Lambda environment variables from AWS Secrets Manager

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/creating-aws-lambda-environmental-variables-from-aws-secrets-manager/

This post is written by Andy Hall, Senior Solutions Architect.

AWS Lambda layers and extensions are used by third-party software providers for monitoring Lambda functions. A monitoring solution needs environmental variables to provide configuration information to send metric information to an endpoint.

Managing this information as environmental variables across thousands of Lambda functions creates operational overhead. Instead, you can use the approach in this blog post to create environmental variables dynamically from information hosted in AWS Secrets Manager.

This can help avoid managing secret rotation for individual functions. It ensures that values stay encrypted until runtime, and abstracts away the management of the environmental variables.

Overview

This post shows how to create a Lambda layer for Node.js, Python, Ruby, Java, and .NET Core runtimes. It retrieves values from Secrets Manager and converts the secret into an environmental variable that can be used by other layers and functions. The Lambda layer uses a wrapper script to fetch information from Secrets Manager and create environmental variables.

Solution architecture

The steps in the process are as follows:

  1. The Lambda service responds to an event and initializes the Lambda context.
  2. The wrapper script is called as part of the Lambda init phase.
  3. The wrapper script calls a Golang executable passing in the ARN for the secret to retrieve.
  4. The Golang executable uses the Secrets Manager API to retrieve the decrypted secret.
  5. The wrapper script converts the information into environmental variables and calls the next step in processing.

All of the code for this post is available from this GitHub repo.

The wrapper script

The wrapper script is the main entry-point for the extension and is called by the Lambda service as part of the init phase. During this phase, the wrapper script will read in basic information from the environment and call the Golang executable. If there was an issue with the Golang executable, the wrapper script will log a statement and exit with an error.

# Get the secret value by calling the Go executable
values=$(${fullPath}/go-retrieve-secret -r "${region}" -s "${secretArn}" -a "${roleName}" -t ${timeout})
last_cmd=$?

# Verify that the last command was successful
if [[ ${last_cmd} -ne 0 ]]; then
    echo "Failed to setup environment for Secret ${secretArn}"
    exit 1
fi

Golang executable

This uses Golang to invoke the AWS APIs since the Lambda execution environment does natively provide the AWS Command Line Interface. The Golang executable can be included in a layer so that the layer works with a number of Lambda runtimes.

The Golang executable captures and validates the command line arguments to ensure that required parameters are supplied. If Lambda does not have permissions to read and decrypt the secret, you can supply an ARN for a role to assume.

The following code example shows how the Golang executable retrieves the necessary information to assume a role using the AWS Security Token Service:

client := sts.NewFromConfig(cfg)

return client.AssumeRole(ctx,
    &sts.AssumeRoleInput{
        RoleArn: &roleArn,
        RoleSessionName: &sessionName,
    },
)

After obtaining the necessary permissions, the secret can be retrieved using the Secrets Manager API. The following code example uses the new credentials to create a client connection to Secrets Manager and the secret:

client := secretsmanager.NewFromConfig(cfg, func(o *secretsmanager.Options) {
    o.Credentials = aws.NewCredentialsCache(credentials.NewStaticCredentialsProvider(*assumedRole.Credentials.AccessKeyId, *assumedRole.Credentials.SecretAccessKey, *assumedRole.Credentials.SessionToken))
})
return client.GetSecretValue(ctx, &secretsmanager.GetSecretValueInput{
    SecretId: aws.String(secretArn),
})

After retrieving the secret, the contents must be converted into a format that the wrapper script can use. The following sample code covers the conversion from a secret string to JSON by storing the data in a map. Once the data is in a map, a loop is used to output the information as key-value pairs.

// Convert the secret into JSON
var dat map[string]interface{}

// Convert the secret to JSON
if err := json.Unmarshal([]byte(*result.SecretString), &dat); err != nil {
    fmt.Println("Failed to convert Secret to JSON")
    fmt.Println(err)
    panic(err)
}

// Get the secret value and dump the output in a manner that a shell script can read the
// data from the output
for key, value := range dat {
    fmt.Printf("%s|%s\n", key, value)
}

Conversion to environmental variables

After the secret information is retrieved by using Golang, the wrapper script can now loop over the output, populate a temporary file with export statements, and execute the temporary file. The following code covers these steps:

# Read the data line by line and export the data as key value pairs 
# and environmental variables
echo "${values}" | while read -r line; do 
    
    # Split the line into a key and value
    ARRY=(${line//|/ })

    # Capture the kay value
    key="${ARRY[0]}"

    # Since the key had been captured, no need to keep it in the array
    unset ARRY[0]

    # Join the other parts of the array into a single value.  There is a chance that
    # The split man have broken the data into multiple values.  This will force the
    # data to be rejoined.
    value="${ARRY[@]}"
    
    # Save as an env var to the temp file for later processing
    echo "export ${key}=\"${value}\"" >> ${tempFile}
done

# Source the temp file to read in the env vars
. ${tempFile}

At this point, the information stored in the secret is now available as environmental variables to layers and the Lambda function.

Deployment

To deploy this solution, you must build on an instance that is running an Amazon Linux 2 AMI. This ensures that the compiled Golang executable is compatible with the Lambda execution environment.

The easiest way to deploy this solution is from an AWS Cloud9 environment but you can also use an Amazon EC2 instance. To build and deploy the solution into your environment, you need the ARN of the secret that you want to use. A build script is provided to ease deployment and perform compilation, archival, and AWS CDK execution.

To deploy, run:

./build.sh <ARN of the secret to use>

Once the build is complete, the following resources are deployed into your AWS account:

  • A Lambda layer (called get-secrets-layer)
  • A second Lambda layer for testing (called second-example-layer)
  • A Lambda function (called example-get-secrets-lambda)

Testing

To test the deployment, create a test event to send to the new example-get-secrets-lambda Lambda function using the AWS Management Console. The test Lambda function uses both the get-secrets-layer and second-example-layer Lambda layers, and the secret specified from the build. This function logs the values of environmental variables that were created by the get-secrets-layer and second-example-layer layers:

The secret contains the following information:

{
  "EXAMPLE_CONNECTION_TOKEN": "EXAMPLE AUTH TOKEN",
  "EXAMPLE_CLUSTER_ID": "EXAMPLE CLUSTER ID",
  "EXAMPLE_CONNECTION_URL": "EXAMPLE CONNECTION URL",
  "EXAMPLE_TENANT": "EXAMPLE TENANT",
  "AWS_LAMBDA_EXEC_WRAPPER": "/opt/second-example-layer"
}

This is the Python code for the example-get-secrets-lambda function:

import os
import json
import sys

def lambda_handler(event, context):
    print(f"Got event in main lambda [{event}]",flush=True)
    
    # Return all of the data
    return {
        'statusCode': 200,
        'layer': {
            'EXAMPLE_AUTH_TOKEN': os.environ.get('EXAMPLE_AUTH_TOKEN', 'Not Set'),
            'EXAMPLE_CLUSTER_ID': os.environ.get('EXAMPLE_CLUSTER_ID', 'Not Set'),
            'EXAMPLE_CONNECTION_URL': os.environ.get('EXAMPLE_CONNECTION_URL', 'Not Set'),
            'EXAMPLE_TENANT': os.environ.get('EXAMPLE_TENANT', 'Not Set'),
            'AWS_LAMBDA_EXEC_WRAPPER': os.environ.get('AWS_LAMBDA_EXEC_WRAPPER', 'Not Set')
        },
        'secondLayer': {
            'SECOND_LAYER_EXECUTE': os.environ.get('SECOND_LAYER_EXECUTE', 'Not Set')
        }
    }

When running a test using the AWS Management Console, you see the following response returned from the Lambda in the AWS Management Console:

{
  "statusCode": 200,
  "layer": {
    "EXAMPLE_AUTH_TOKEN": "EXAMPLE AUTH TOKEN",
    "EXAMPLE_CLUSTER_ID": "EXAMPLE CLUSTER ID",
    "EXAMPLE_CONNECTION_URL": "EXAMPLE CONNECTION URL",
    "EXAMPLE_TENANT": "EXAMPLE TENANT",
    "AWS_LAMBDA_EXEC_WRAPPER": "/opt/second-example-layer"
  },
  "secondLayer": {
    "SECOND_LAYER_EXECUTE": "true"
  }
}

When the secret changes, there is a delay before those changes are available to the Lambda layers and function. This is because the layer only executes in the init phase of the Lambda lifecycle. After the Lambda execution environment is recreated and initialized, the layer executes and creates environmental variables with the new secret information.

Conclusion

This solution provides a way to convert information from Secrets Manager into Lambda environment variables. By following this approach, you can centralize the management of information through Secrets Manager, instead of at the function level.

For more information about the Lambda lifecycle, see the Lambda execution environment lifecycle documentation.

The code for this post is available from this GitHub repo.

For more serverless learning resources, visit Serverless Land.

Accelerating serverless development with AWS SAM Accelerate

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/accelerating-serverless-development-with-aws-sam-accelerate/

Building a serverless application changes the way developers think about testing their code. Previously, developers would emulate the complete infrastructure locally and only commit code ready for testing. However, with serverless, local emulation can be more complex.

In this post, I show you how to bypass most local emulation by testing serverless applications in the cloud against production services using AWS SAM Accelerate. AWS SAM Accelerate aims to increase infrastructure accuracy for testing with sam sync, incremental builds, and aggregated feedback for developers. AWS SAM Accelerate brings the developer to the cloud and not the cloud to the developer.

AWS SAM Accelerate

The AWS SAM team has listened to developers wanting a better way to emulate the cloud on their local machine and we believe that testing against the cloud is the best path forward. With that in mind, I am happy to announce the beta release of AWS SAM Accelerate!

Previously, the latency of deploying after each change has caused developers to seek other options. AWS SAM Accelerate is a set of features to reduce that latency and enable developers to test their code quickly against production AWS services in the cloud.

To demonstrate the different options, this post uses an example application called “Blog”. To follow along, create your version of the application by downloading the demo project. Note, you need the latest version of AWS SAM and Python 3.9 installed. AWS SAM Accelerate works with other runtimes, but this example uses Python 3.9.

After installing the pre-requisites, set up the demo project with the following commands:

  1. Create a folder for the project called blog
    mkdir blog && cd blog
  2. Initialize a new AWS SAM project:
    sam init
  3. Chose option 2 for Custom Template Location.
  4. Enter https://github.com/aws-samples/aws-sam-accelerate-demo as the location.

AWS SAM downloads the sample project into the current folder. With the blog application in place, you can now try out AWS SAM Accelerate.

AWS SAM sync

The first feature of AWS SAM Accelerate is a new command called sam sync. This command synchronizes your project declared in an AWS SAM template to the AWS Cloud. However, sam sync differentiates between code and configuration.

AWS SAM defines code as the following:

Anything else is considered configuration. The following description of the sam sync options explains how sam sync differentiates between configuration synchronization and code synchronization. The resulting patterns are the fastest way to test code in the cloud with AWS SAM.

Using sam sync (no options)

The sam sync command with no options deploys or updates all infrastructure and code like the sam deploy command. However, unlike sam deploy, sam sync bypasses the AWS CloudFormation changeset process. To see this, run:

sam sync --stack-name blog
AWS SAM sync with no options

AWS SAM sync with no options

First, sam sync builds the code using the sam build command and then the application is synchronized to the cloud.

Successful sync

Successful sync

Using SAM sync code, resource, resource-id flags

The sam sync command can also synchronize code changes to the cloud without updating the infrastructure. This code synchronization uses the service APIs and bypasses CloudFormation, allowing AWS SAM to update the code in seconds instead of minutes.

To synchronize code, use the --code flag, which instructs AWS SAM to sync all the code resources in the stack:

sam sync --stack-name blog --code
AWS SAM sync --code

AWS SAM sync with the code flag

The sam sync command verifies each of the code types present and synchronizes the sources to the cloud. This example uses an API Gateway REST API and two Lambda functions. AWS SAM skips the REST API because there is no external OpenAPI file for this project. However, the Lambda functions and their dependencies are synchronized.

You can limit the synchronized resources by using the --resource flag with the --code flag:

sam sync --stack-name blog --code --resource AWS::Serverless::Function
SAM sync specific resource types

SAM sync specific resource types

This command limits the synchronization to Lambda functions. Other available resources are AWS::Serverless::Api, AWS::Serverless::HttpApi, and AWS::Serverless::StateMachine.

You can target one specific resource with the --resource-id flag to get more granular:

sam sync --stack-name blog --code --resource-id HelloWorldFunction
SAM sync specific resource

SAM sync specific resource

This time sam sync ignores the GreetingFunction and only updates the HelloWorldFunction declared with the command’s --resource-id flag.

Using the SAM sync watch flag

The sam sync --watch option tells AWS SAM to monitor for file changes and automatically synchronize when changes are detected. If the changes include configuration changes, AWS SAM performs a standard synchronization equivalent to the sam sync command. If the changes are code only, then AWS SAM synchronizes the code with the equivalent of the sam sync --code command.

The first time you run the sam sync command with the --watch flag, AWS SAM ensures that the latest code and infrastructure are in the cloud. It then monitors for file changes until you quit the command:

sam sync --stack-name blog --watch
Initial sync

Initial sync

To see a change, modify the code in the HelloWorldFunction (hello_world/app.py) by updating the response to the following:

return {
  "statusCode": 200,
  "body": json.dumps({
    "message": "hello world, how are you",
    # "location": ip.text.replace("\n", "")
  }),
}

Once you save the file, sam sync detects the change and syncs the code for the HelloWorldFunction to the cloud.

AWS SAM detects changes

AWS SAM detects changes

Auto dependency layer nested stack

During the initial sync, there is a logical resource name called AwsSamAutoDependencyLayerNestedStack. This feature helps to synchronize code more efficiently.

When working with Lambda functions, developers manage the code for the Lambda function and any dependencies required for the Lambda function. Before AWS SAM Accelerate, if a developer does not create a Lambda layer for dependencies, then the dependencies are re-uploaded with the function code on every update. However, with sam sync, the dependencies are automatically moved to a temporary layer to reduce latency.

Auto dependency layer in change set

Auto dependency layer in change set

During the first synchronization, sam sync creates a single nested stack that maintains a Lambda layer for each Lambda function in the stack.

Auto dependency layer in console

Auto dependency layer in console

These layers are only updated when the dependencies for one of the Lambda functions are updated. To demonstrate, change the requirements.txt (greeting/requirements.txt) file for the GreetingFunction to the following:

Requests
boto3

AWS SAM detects the change, and the GreetingFunction and its temporary layer are updated:

Auto layer synchronized

Auto dependency layer synchronized

The Lambda function changes because the Lambda layer version must be updated.

Incremental builds with sam build

The second feature of AWS SAM Accelerate is an update to the SAM build command. This change separates the cache for dependencies from the cache for the code. The build command now evaluates these separately and only builds artifacts that have changed.

To try this out, build the project with the cached flag:

sam build --cached
The first build establishes cache

The first build establishes cache

The first build recognizes that there is no cache and downloads the dependencies and builds the code. However, when you rerun the command:

The second build uses existing cached artifacts

The second build uses existing cached artifacts

The sam build command verifies that the dependencies have not changed. There is no need to download them again so it builds only the application code.

Finally, update the requirements file for the HelloWorldFunction (hello_w0rld/requirements.txt) to:

Requests
boto3

Now rerun the build command:

AWS SAM build detects dependency changes

AWS SAM build detects dependency changes

The sam build command detects a change in the dependency requirements and rebuilds the dependencies and the code.

Aggregated feedback for developers

The final part of AWS SAM Accelerate’s beta feature set is aggregating logs for developer feedback. This feature is an enhancement to the already existing sam logs command. In addition to pulling Amazon CloudWatch Logs or the Lambda function, it is now possible to retrieve logs for API Gateway and traces from AWS X-Ray.

To test this, start the sam logs:

sam logs --stack-name blog --include-traces --tail

Invoke the HelloWorldApi endpoint returned in the outputs on syncing:

curl https://112233445566.execute-api.us-west-2.amazonaws.com/Prod/hello

The sam logs command returns logs for the AWS Lambda function, Amazon API Gateway REST execution logs, and AWS X-Ray traces.

AWS Lambda logs from Amazon CloudWatch

AWS Lambda logs from Amazon CloudWatch

Amazon API Gateway execution logs from Amazon CloudWatch

Amazon API Gateway execution logs from Amazon CloudWatch

Traces from AWS X-Ray

Traces from AWS X-Ray

The full picture

Development diagram for AWS SAM Accelerate

Development diagram for AWS SAM Accelerate

With AWS SAM Accelerate, creating and testing an application is easier and faster. To get started:

  1. Start a new project:
    sam init
  2. Synchronize the initial project with a development environment:
    sam sync --stack-name <project name> --watch
  3. Start monitoring for logs:
    sam logs --stack-name <project name> --include-traces --tail
  4. Test using response data or logs.
  5. Iterate.
  6. Rinse and repeat!

Some caveats

AWS SAM Accelerate is in beta as of today. The team has worked hard to implement a solid minimum viable product (MVP) to get feedback from our community. However, there are a few caveats.

  1. Amazon State Language (ASL) code updates for Step Functions does not currently support DefinitionSubstitutions.
  2. API Gateway OpenAPI template must be defined in the DefiitionUri parameter and does not currently support pseudo parameters and intrinsic functions at this time
  3. The sam logs command only supports execution logs on REST APIs and access logs on HTTP APIs.
  4. Function code cannot be inline and must be defined as a separate file in the CodeUri parameter.

Conclusion

When testing serverless applications, developers must get to the cloud as soon as possible. AWS SAM Accelerate helps developers escape from emulating the cloud locally and move to the fidelity of testing in the cloud.

In this post, I walk through the philosophy of why the AWS SAM team built AWS SAM Accelerate. I provide an example application and demonstrate the different features designed to remove barriers from testing in the cloud.

We invite the serverless community to help improve AWS SAM for building serverless applications. As with AWS SAM and the AWS SAM CLI (which includes AWS SAM Accelerate), this project is open source and you can contribute to the repository.

For more serverless content, visit Serverless Land.
Simplifying Multi-account CI/CD Deployments using AWS Proton

Post Syndicated from Marvin Fernandes original https://aws.amazon.com/blogs/architecture/simplifying-multi-account-ci-cd-deployments-using-aws-proton/

Many large enterprises, startups, and public sector entities maintain different deployment environments within multiple Amazon Web Services (AWS) accounts to securely develop, test, and deploy their applications. Maintaining separate AWS accounts for different deployment stages is a standard practice for organizations. It helps developers limit the blast radius in case of failure when deploying updates to an application, and provides for more resilient and distributed systems.

Typically, the team that owns and maintains these environments (the platform team) is segregated from the development team. A platform team performs critical activities. These can include setting infrastructure and governance standards, keeping patch levels up to date, and maintaining security and monitoring standards. Development teams are responsible for writing the code, performing appropriate testing, and pushing code to repositories to initiate deployments. The development teams are focused more on delivering their application and less on the infrastructure and networking that ties them together. The segregation of duties and use of multi-account environments are effective from a regulatory and development standpoint. But monitoring, maintaining, and enabling the safe release to these environments can be cumbersome and error prone.

In this blog, you will see how to simplify multi-account deployments in an environment that is segregated between platform and development teams. We will show how you can use one consistent and standardized continuous delivery pipeline with AWS Proton.

Challenges with multi-account deployment

For platform teams, maintaining these large environments at different stages in the development lifecycle and within separate AWS accounts can be tedious. The platform teams must ensure that certain security and regulatory requirements (like networking or encryption standards) are implemented in each separate account and environment. When working in a multi-account structure, AWS Identity and Access Management (IAM) permissions and cross-account access management can be a challenge for many account administrators. Many organizations rely on specific monitoring metrics and tagging strategies to perform basic functions. The platform team is responsible for enforcing these processes and implementing these details repeatedly across multiple accounts. This is a pain point for many infrastructure administrators or platform teams.

Platform teams are also responsible for ensuring a safe and secure application deployment pipeline. To do this, they isolate deployment and production environments from one another limiting the blast radius in case of failure. Platform teams enforce the principle of least privilege on each account, and implement proper testing and monitoring standards across the deployment pipeline.

Instead of focusing on the application and code, many developers face challenges complying with these rigorous security and infrastructure standards. This results in limited access to resources for developers. Delays come with reliance on administrators to deploy application code into production. This can lead to lags in deployment of updated code.

Deployment using AWS Proton

The ownership for infrastructure lies with the platform teams. They set the standards for security, code deployment, monitoring, and even networking. AWS Proton is an infrastructure provisioning and deployment service for serverless and container-based applications. Using AWS Proton, the platform team can provide their developers with a highly customized and catered “platform as a service” experience. This allows developers to focus their energy on building the best application, rather than spending time on orchestration tools. Platform teams can similarly focus on building the best platform for that application.

With AWS Proton, developers use predefined templates. With only a few input parameters, infrastructure can be provisioned and code deployed in an effective pipeline. This way you can get your application running and updated more quickly, see Figure 1.

Figure 1. Platform and development team roles when using AWS Proton

Figure 1. Platform and development team roles when using AWS Proton

AWS Proton allows you to deploy any serverless or container-based application across multiple accounts. You can define infrastructure standards and effective continuous delivery pipelines for your organization. Proton breaks down the infrastructure into environment and service (“infrastructure as code” templates).

In Figure 2, platform teams provide a service template of a secure environment to host a microservices application on Amazon Elastic Container Service (Amazon ECS) and AWS Fargate. The environment template contains infrastructure that is shared across services. This includes the networking configuration: Amazon Virtual Private Cloud (VPC), subnets, route tables, Internet Gateway, security groups, and ECS cluster definition for the Fargate service.

The service template provides details of the service. It includes the container task definitions, monitoring and logging definitions, and an effective continuous delivery pipeline. Using the environment and service template definitions, development teams can define the microservices that are running on Amazon ECS. They can deploy their code following the continuous integration and continuous delivery (CI/CD) pipeline.

Figure 2. Platform teams provision environment and service infrastructure as code templates in AWS Proton management account

Figure 2. Platform teams provision environment and service infrastructure as code templates in AWS Proton management account

Multi-account CI/CD deployment

For Figures 3 and 4, we used publicly available templates and created three separate AWS accounts: the AWS Proton management account, development account, and production environment accounts. Additional accounts may be added based on your use case and security requirements. As shown in Figure 3, the AWS Proton service account contains the environment, service, and pipeline templates. It also provides the connection to other accounts within the organization. The development and production accounts follow the structure of a development pipeline for a typical organization.

AWS Proton alleviates complicated cross-account policies by using a secure “environment account connection” feature. With environment account connections, platform administrators can give AWS Proton permissions to provision infrastructure in other accounts. They create an IAM role and specify a set of permissions in the target account. This enables Proton to assume the role from the management account to build resources in the target accounts.

AWS Key Management Service (KMS) policies can also be hard to manage in multi-account deployments. Proton reduces managing cross-account KMS permissions. In an AWS Proton management account, you can build a pipeline using a single artifact repository. You can also extend the pipeline to additional accounts from a single source of truth. This feature can be helpful when accounts are located in different Regions, due to regulatory requirements for example.

Figure 3. AWS Proton uses cross-account policies and provisions infrastructure in development and production accounts with environment connection feature

Figure 3. AWS Proton uses cross-account policies and provisions infrastructure in development and production accounts with environment connection feature

Once the environment and service templates are defined in the AWS Proton management account, the developer selects the templates. Proton then provisions the infrastructure, and the continuous delivery pipeline that will deploy the services to each separate account.

Developers commit code to a repository, and the pipeline is responsible for deploying to the different deployment stages. You don’t have to worry about any of the environment connection workflows. Proton allows platform teams to provide a single pipeline definition to deploy the code into multiple different accounts without any additional account level information. This standardizes the deployment process and implements effective testing and staging policies across the organization.

Platform teams can also inject manual approvals into the pipeline so they can control when a release is deployed. Developers can define tests that initiate after a deployment to ensure the validity of releases before moving to a production environment. This simplifies application code deployment in an AWS multi-account environment and allows updates to be deployed more quickly into production. The resulting deployed infrastructure is shown in Figure 4.

Figure 4. AWS Proton deploys service into multi-account environment through standardized continuous delivery pipeline

Figure 4. AWS Proton deploys service into multi-account environment through standardized continuous delivery pipeline

Conclusion

In this blog, we have outlined how using AWS Proton can simplify handling multi-account deployments using one consistent and standardized continuous delivery pipeline. AWS Proton addresses multiple challenges in the segregation of duties between developers and platform teams. By having one uniform resource for all these accounts and environments, developers can develop and deploy applications faster, while still complying with infrastructure and security standards.

For further reading:

Getting started with Proton
Identity and Access Management for AWS Proton
Proton administrative guide

Monitoring and tuning federated GraphQL performance on AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/monitoring-and-tuning-federated-graphql-performance-on-aws-lambda/

This post is written by Krzysztof Lis, Senior Software Development Engineer, IMDb.

Our federated GraphQL at IMDb distributes requests across 19 subgraphs (graphlets). To ensure reliability for customers, IMDb monitors availability and performance across the whole stack. This article focuses on this challenge and concludes a 3-part federated GraphQL series:

  • Part 1 presents the migration from a monolithic REST API to a federated GraphQL (GQL) endpoint running on AWS Lambda.
  • Part 2 describes schema management in federated GQL systems.

This presents an approach towards performance tuning. It compares graphlets with the same logic and different runtime (for example, Java and Node.js) and shows best practices for AWS Lambda tuning.

The post describes IMDb’s test strategy that emphasizes the areas of ownership for the Gateway and Graphlet teams. In contrast to the legacy monolithic system described in part 1, the federated GQL gateway does not own any business logic. Consequently, the gateway integration tests focus solely on platform features, leaving the resolver logic entirely up to the graphlets.

Monitoring and alarming

Efficient monitoring of a distributed system requires you to track requests across all components. To correlate service issues with issues in the gateway or other services, you must pass and log the common request ID.

Capture both error and latency metrics for every network call. In Lambda, you cannot send a response to the client until all work for that request is complete. As a result, this can add latency to a request.

The recommended way to capture metrics is Amazon CloudWatch embedded metric format (EMF). This scales with Lambda and helps avoid throttling by the Amazon CloudWatch PutMetrics API. You can also search and analyze your metrics and logs more easily using CloudWatch Logs Insights.

Lambda configured timeouts emit a Lambda invocation error metric, which can make it harder to separate timeouts from errors thrown during invocation. By specifying a timeout in-code, you can emit a custom metric to alarm on to treat timeouts differently from unexpected errors. With EMF, you can flush metrics before timing out in code, unlike the Lambda-configured timeout.

Running out of memory in a Lambda function also appears as a timeout. Use CloudWatch Insights to see if there are Lambda invocations that are exceeding the memory limits.

You can enable AWS X-Ray tracing for Lambda with a small configuration change to enable tracing. You can also trace components like SDK calls or custom sub segments.

Gateway integration tests

The Gateway team wants tests to be independent from the underlying data served by the graphlets. At the same time, they must test platform features provided by the Gateway – such as graphlet caching.

To simulate the real gateway-graphlet integration, IMDb uses a synthetic test graphlet that serves mock data. Given the graphlet’s simplicity, this reduces the risk of unreliable graphlet data. We can run tests asserting only platform features with the assumption of stable and functional, improving confidence that failing tests indicate issues with the platform itself.

This approach helps to reduce false positives in pipeline blockages and improves the continuous delivery rate. The gateway integration tests are run against the exposed endpoint (for example, a content delivery network) or by invoking the gateway Lambda function directly and passing the appropriate payload.

The former approach allows you to detect potential issues with the infrastructure setup. This is useful when you use infrastructure as code (IaC) tools like AWS CDK. The latter further narrows down the target of the tests to the gateway logic, which may be appropriate if you have extensive infrastructure monitoring and testing already in place.

Graphlet integration tests

The Graphlet team focuses only on graphlet-specific features. This usually means the resolver logic for the graph fields they own in the overall graph. All the platform features – including query federation and graphlet response caching – are already tested by the Gateway Team.

The best way to test the specific graphlet is to run the test suite by directly invoking the Lambda function. If there is any issue with the gateway itself, it does cause a false-positive failure for the graphlet team.

Load tests

It’s important to determine the maximum traffic volume your system can handle before releasing to production. Before the initial launch and before any high traffic events (for example, the Oscars or Golden Globes), IMDb conducts thorough load testing of our systems.

To perform meaningful load testing, the workload captures traffic logs to IMDb pages. We later replay the real customer traffic at the desired transaction-per-second (TPS) volume. This ensures that our tests approximate real-life usage. It reduces the risk of skewing test results due to over-caching and disproportionate graphlet usage. Vegeta is an example of a tool you can use to run the load test against your endpoint.

Canary tests

Canary testing can also help ensure high availability of an endpoint. The canary produces the traffic. This is a configurable script that runs on a schedule. You configure the canary script to follow the same routes and perform the same actions as a user, which allows you to continually verify the user experience even without live traffic.

Canaries should emit success and failure metrics that you can alarm on. For example, if a canary runs 100 times per minute and the success rate drops below 90% in three consecutive data points, you may choose to notify a technician about a potential issue.

Compared with integration tests, canary tests run continuously and do not require any code changes to trigger. They can be a useful tool to detect issues that are introduced outside the code change. For example, through manual resource modification in the AWS Management Console or an upstream service outage.

Performance tuning

There is a per-account limit on the number of concurrent Lambda invocations shared across all Lambda functions in a single account. You can help to manage concurrency by separating high-volume Lambda functions into different AWS accounts. If there is a traffic surge to any one of the Lambda functions, this isolates the concurrency used to a single AWS account.

Lambda compute power is controlled by the memory setting. With more memory comes more CPU. Even if a function does not require much memory, you can adjust this parameter to get more CPU power and improve processing time.

When serving real-time traffic, Provisioned Concurrency in Lambda functions can help to avoid cold start latency. (Note that you should use max, not average for your auto scaling metric to keep it more responsive for traffic increases.) For Java functions, code in static blocks is run before the function is invoked. Provisioned Concurrency is different to reserved concurrency, which sets a concurrency limit on the function and throttles invocations above the hard limit.

Use the maximum number of concurrent executions in a load test to determine the account concurrency limit for high-volume Lambda functions. Also, configure a CloudWatch alarm for when you are nearing the concurrency limit for the AWS account.

There are concurrency limits and burst limits for Lambda function scaling. Both are per-account limits. When there is a traffic surge, Lambda creates new instances to handle the traffic. “Burst limit = 3000” means that the first 3000 instances can be obtained at a much faster rate (invocations increase exponentially). The remaining instances are obtained at a linear rate of 500 per minute until reaching the concurrency limit.

An alternative way of thinking this is that the rate at which concurrency can increase is 500 per minute with a burst pool of 3000. The burst limit is fixed, but the concurrency limit can be increased by requesting a quota increase.

You can further reduce cold start latency by removing unused dependencies, selecting lightweight libraries for your project, and favoring compile-time over runtime dependency injection.

Impact of Lambda runtime on performance

Choice of runtime impacts the overall function performance. We migrated a graphlet from Java to Node.js with complete feature parity. The following graph shows the performance comparison between the two:

Performance graph

To illustrate the performance difference, the graph compares the slowest latencies for Node.js and Java – the P80 latency for Node.js was lower than the minimal latency we recorded for Java.

Conclusion

There are multiple factors to consider when tuning a federated GQL system. You must be aware of trade-offs when deciding on factors like the runtime environment of Lambda functions.

An extensive testing strategy can help you scale systems and narrow down issues quickly. Well-defined testing can also keep pipelines clean of false-positive blockages.

Using CloudWatch EMF helps to avoid PutMetrics API throttling and allows you to run CloudWatch Logs Insights queries against metric data.

For more serverless learning resources, visit Serverless Land.

Building a difference checker with Amazon S3 and AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/building-a-difference-checker-with-amazon-s3-and-aws-lambda/

When saving different versions of files or objects, it can be useful to detect and log the differences between the versions automatically. A difference checker tool can detect changes in JSON files for configuration changes, or log changes in documents made by users.

This blog post shows how to build and deploy a scalable difference checker service using Amazon S3 and AWS Lambda. The example application uses the AWS Serverless Application Model (AWS SAM), enabling you to deploy the application more easily in your own AWS account.

This walkthrough creates resources covered in the AWS Free Tier but usage beyond the Free Tier allowance may incur cost. To set up the example, visit the GitHub repo and follow the instructions in the README.md file.

Overview

By default in S3, when you upload an object with the same name as an existing object, the new object overwrites the existing one. However, when you enable versioning in a S3 bucket, the service stores every version of an object. Versioning provides an effective way to recover objects in the event of accidental deletion or overwriting. It also provides a way to detect changes in objects, since you can compare the latest version to previous versions.

In the example application, the S3 bucket triggers a Lambda function every time an object version is unloaded. The Lambda function compares the latest version with the last version and then writes the differences to Amazon CloudWatch Logs.

Additionally, the application uses a configurable environment variable to determine how many versions of the object to retain. By default, it keeps the latest three versions. The Lambda function deletes versions that are earlier than the configuration allows, providing an effective way to implement object life cycling.

This shows the application flow when multiple versions of an object are uploaded:

Application flow

  1. When v1 is uploaded, there is no previous version to compare against.
  2. When v2 is uploaded, the Lambda function logs the differences compared with v1.
  3. When v3 is uploaded, the Lambda function logs the differences compared with v2.
  4. When v4 is uploaded, the Lambda function logs the differences compared with v3. It then deletes v1 of the object, since it is earlier than the configured setting.

Understanding the AWS SAM template

The application’s AWS SAM template configures the bucket with versioning enabled using the VersioningConfiguration attribute:

  SourceBucket:
    Type: AWS::S3::Bucket
    Properties:
      BucketName: !Ref BucketName
      VersioningConfiguration:
        Status: Enabled      

It defines the Lambda function with an environment variable KEEP_VERSIONS, which determines how many versions of an object to retain:

  S3ProcessorFunction:
    Type: AWS::Serverless::Function 
    Properties:
      CodeUri: src/
      Handler: app.handler
      Runtime: nodejs14.x
      MemorySize: 128
      Environment:
        Variables:
          KEEP_VERSIONS: 3

The template uses an AWS SAM policy template to provide the Lambda function with an S3ReadPolicy to the objects in the bucket. The version handling logic requires s3:ListBucketVersions permission on the bucket and s3:DeleteObjectVersion permission on the objects in the bucket. It’s important to note which permissions apply to the bucket and which apply to the objects within the bucket. The template defines these three permission types in the function’s policy:

      Policies:
        - S3ReadPolicy:
            BucketName: !Ref BucketName      
        - Statement:
          - Sid: VersionsPermission
            Effect: Allow
            Action:
            - s3:ListBucketVersions
            Resource: !Sub "arn:${AWS::Partition}:s3:::${BucketName}" 
        - Statement:
          - Sid: DeletePermission
            Effect: Allow
            Action:
            - s3:DeleteObject
            - s3:DeleteObjectVersion
            Resource: !Sub "arn:${AWS::Partition}:s3:::${BucketName}/*" 

The example application only works for text files but you can use the same logic to process other file types. The event definition ensures that only objects ending in ‘.txt’ invoke the Lambda function:

      Events:
        FileUpload:
          Type: S3
          Properties:
            Bucket: !Ref SourceBucket
            Events: s3:ObjectCreated:*
            Filter: 
              S3Key:
                Rules:
                  - Name: suffix
                    Value: '.txt'     

Processing events from the S3 bucket

S3 sends events to the Lambda function when objects are created. The event contains metadata about the objects but not the contents of the object. It’s good practice to separate the business logic of the function from the Lambda handler, so the generic handler in app.js iterates through the event’s records and calls the custom logic for each record:

const { processS3 } = require('./processS3')

exports.handler = async (event) => {
  console.log (JSON.stringify(event, null, 2))

  await Promise.all(
    event.Records.map(async (record) => {
      try {
        await processS3(record)
      } catch (err) {
        console.error(err)
      }
    })
  )
}

The processS3.js file contains a function that fetches the object versions in the bucket and sorts the event data received. The listObjectVersions method of the S3 API requires the s3:ListBucketVersions permission, as provided in the AWS SAM template:

    // Decode URL-encoded key
    const Key = decodeURIComponent(record.s3.object.key.replace(/\+/g, " "))

    // Get the list of object versions
    const data = await s3.listObjectVersions({
      Bucket: record.s3.bucket.name,
      Prefix: Key
    }).promise()

   // Sort versions by date (ascending by LastModified)
    const versions = data.Versions
    const sortedVersions = versions.sort((a,b) => new Date(a.LastModified) - new Date(b.LastModified))

Finally, the compareS3.js file contains a function that loads the latest two versions of the S3 object and uses the Diff npm library to compare:

const compareS3 = async (oldVersion, newVersion) => {
  try {
    console.log ({oldVersion, newVersion})

    // Get original text from objects 
    const oldObject = await s3.getObject({ Bucket: oldVersion.BucketName, Key: oldVersion.Key }).promise()
    const newObject = await s3.getObject({ Bucket: newVersion.BucketName, Key: newVersion.Key }).promise()

    // Convert buffers to strings
    const oldFile = oldObject.Body.toString()
    const newFile = newObject.Body.toString()

    // Use diff library to compare files (https://www.npmjs.com/package/diff)
    return Diff.diffWords(oldFile, newFile)

  } catch (err) {
    console.error('compareS3: ', err)
  }
}

Life-cycling earlier versions of an S3 object

You can use an S3 Lifecycle configuration to apply rules automatically based on object transition actions. Using this approach, you can expire objects based upon age and the S3 service processes the deletion asynchronously. Lifecyling with rules is entirely managed by S3 and does not require any custom code. This implementation uses a different approach, using code to delete objects based on number of retained versions instead of age.

When versioning is enabled on a bucket, S3 adds a VersionId attribute to an object when it is created. This identifier is a random string instead of a sequential identifier. Listing the versions of an object also returns a LastModified attribute, which can be used to determine the order of the versions. The length of the response array also indicates the number of versions available for an object:

[
  {
    Key: 'test.txt',
    VersionId: 'IX_tyuQrgKpMFfq5YmLOlrtaleRBQRE',
    IsLatest: false,
    LastModified: 2021-08-01T18:48:50.000Z,
  },
  {
    Key: 'test.txt',
    VersionId: 'XNpxNgUYhcZDcI9Q9gXCO9_VRLlx1i.',
    IsLatest: false,
    LastModified: 2021-08-01T18:52:58.000Z,
  },
  {
    Key: 'test.txt',
    VersionId: 'RBk2BUIKcYYt4hNA5hrTVdNit.MDNMZ',
    IsLatest: true,
    LastModified: 2021-08-01T18:53:26.000Z,
  }
]

For convenience, this code adds a sequential version number attribute, determined by sorting the array by date. The deleteS3 function uses the deleteObjects method in the S3 API to delete multiple objects in one action. It builds a params object containing the list of keys for deletion, using the sequential version ID to flag versions for deletion:

const deleteS3 = async (versions) => {

  const params = {
    Bucket: versions[0].BucketName, 
    Delete: {
     Objects: [ ]
    }
  }

  try {
    // Add keys/versions from objects that are process.env.KEEP_VERSIONS behind
    versions.map((version) => {
      if ((versions.length - version.VersionNumber) >= process.env.KEEP_VERSIONS ) {
        console.log(`Delete version ${version.VersionNumber}: versionId = ${version.VersionId}`)
        params.Delete.Objects.push({ 
          Key: version.Key,
          VersionId: version.VersionId
        })
      }
    })

    // Delete versions
    const result = await s3.deleteObjects(params).promise()
    console.log('Delete object result: ', result)

  } catch (err) {
    console.error('deleteS3: ', err)
  }
}

Testing the application

To test this example, upload a sample text file to the S3 bucket by using the AWS Management Console or with the AWS CLI:

aws s3 cp sample.txt s3://myS3bucketname

Modify the test file and then upload again using the same command. This creates a second version in the bucket. Repeat this process multiple times to create more versions of the object. The Lambda function’s log file shows the differences between versions and any deletion activity for earlier versions:

Log activity

You can also test the object locally using the test.js function and supplying a test event. This can be useful for local debugging and testing.

Conclusion

This blog post shows how to create a scalable difference checking tool for objects stored in S3 buckets. The Lambda function is invoked when S3 writes new versions of an object to the bucket. This example also shows how to remove earlier versions of object and define a set number of versions to retain.

I walk through the AWS SAM template for deploying this example application and highlight important S3 API methods in the SDK used in the implementation. I explain how version IDs work in S3 and how to use this in combination with the LastModified date attribute to implement sequential versioning.

To learn more about best practices when using S3 to Lambda, see the Lambda Operator Guide. For more serverless learning resources, visit Serverless Land.

Swiftly Search Metadata with an Amazon S3 Serverless Architecture

Post Syndicated from Jiwan Panjiker original https://aws.amazon.com/blogs/architecture/swiftly-search-metadata-with-an-amazon-s3-serverless-architecture/

As you increase the number of objects in Amazon Simple Storage Service (Amazon S3), you’ll need the ability to search through them and quickly find the information you need.

In this blog post, we offer you a cost-effective solution that uses a serverless architecture to search through your metadata. Using a serverless architecture helps you reduce operational costs because you only pay for what you use.

Our solution is built with Amazon S3 event notifications, AWS Lambda, AWS Glue Catalog, and Amazon Athena. These services allow you to search thousands of objects in an S3 bucket by filenames, object metadata, and object keys. This solution maintains an index in an Apache Parquet file, which optimizes Athena queries to search Amazon S3 metadata. Using this approach makes it straightforward to run queries as needed without the need to ingest data or manage any servers.

Using Athena to search Amazon S3 objects

Amazon S3 stores and retrieves objects for a range of use cases, such as data lakes, websites, cloud-native applications, backups, archive, machine learning, and analytics. When you have an S3 bucket with thousands of files in it, how do you search for and find what you need? The object search box within the Amazon S3 user interface allows you to search by prefix, or you can search using Amazon S3 API’s LIST operation, which only returns 1,000 objects at a time.

A common solution to this issue is to build an external index and search for Amazon S3 objects using the external index. The Indexing Metadata in Amazon Elasticsearch Service Using AWS Lambda and Python and Building and Maintaining an Amazon S3 Metadata Index without Servers blog posts show you how to build this solution with Amazon OpenSearch Service or Amazon DynamoDB.

Our solution stores the external index in Amazon S3 and uses Athena to search the index. Athena makes it straightforward to search Amazon S3 objects without the need to manage servers or introduce another data repository. In the next section, we’ll talk about a few use cases where you can apply this solution.

Metadata search use cases

When your clients upload files to their S3 buckets, you’ll sometimes need to verify the files that were uploaded. You must validate whether you have received all the required information, including metadata such as customer identifier, category, received date, etc. The following examples will make use of this metadata:

  • Searching for a file from a specific date (or) date range
  • Finding all objects uploaded by a given customer identifier
  • Reviewing files for a particular category

The next sections outline how to build a serverless architecture to apply to use cases like these.

Building a serverless file metadata search on AWS

Let’s go through layers that are involved in our serverless architecture solution:

  1. Data ingestion: Set object metadata when objects are uploaded into Amazon S3. This layer uploads objects using the Amazon S3 console, AWS SDK, REST API, and AWS CLI.
  2. Data processing: Integrate Amazon S3 event notifications with Lambda to process S3 events. The AWS Data Wrangler library within Lambda will transform and build the metadata index file.
  3. Data catalog: Use AWS Glue Data Catalog as a central repository to store table definition and add/update business-relevant attributes of the metadata index. AWS Data Wrangler API creates the Apache Parquet files to maintain the AWS Glue Catalog.
  4. Metadata search: Define tables for your metadata and run queries using standard SQL with Athena to get started faster.

Reference architecture

Figure 1 illustrates our approach to implementing serverless file metadata search, which consists of the following steps:

  1. When you create new objects/files in an S3 bucket, the source bucket is configured with Amazon S3 Event Notification events (put, post, copy, etc.). Amazon S3 events provide the metadata information required for further processing and building the metadata index file on the destination bucket.
  2. The S3 event is sent to a Lambda function with necessary permissions on Amazon S3 using a resource-based policy. The Lambda function processes the event with metadata and converts it into an Apache Parquet file, which is then written into a target bucket. The AWS Data Wrangler API transforms and builds the metadata index file. The Lambda layer configures AWS Data Wrangler library for necessary transformations.
  3. AWS Data Wrangler also creates and stores metadata in the AWS Glue Data Catalog. DataFrames are then written into target S3 buckets in Apache Parquet format. The AWS Glue Data Catalog is then updated with necessary metadata. The following example code snippet writes into an example table with columns for year, month, and date for an S3 object.

wr.s3.to_parquet(df=df, path=path, dataset=True, mode="append", partition_cols=["year","month","date"],database="example_database", table="example_table")

  1. With the AWS Glue Data Catalog built, Athena will use AWS Glue crawlers to automatically infer schemas and partitions of the metadata search index. Athena makes it easy to run interactive SQL queries directly into Amazon S3 by using the schema-on-read approach.


Serverless S3 metadata search

Figure 1. Serverless S3 metadata search

Athena charges based on the amount of data scanned for the query. The data being in columnar format and data partitioning will save costs as well as improve performance. Figure 2 provides a sample metadata query result from Athena.

Athena sample metadata query results

Figure 2. Athena sample metadata query results

Conclusion

This blog post shows you how to create a robust metadata index using serverless components. This solution allows you to search files in an S3 bucket by filenames, metadata, and keys.

We showed you how to set up Amazon S3 Event Notifications, Lambda, AWS Glue Catalog, and Athena. You can use this approach to maintain an index in an Apache Parquet file, store it in Amazon S3, and use Athena queries to search S3 metadata.

Our solution requires minimal administration effort. It does not require administration and maintenance of Amazon Elastic Compute Cloud (Amazon EC2) instances, DynamoDB tables, or Amazon OpenSearch Service clusters. Amazon S3 provides scalable storage, high durability, and availability at a low cost. Plus, this solution does not require in-depth knowledge of AWS services. When not in use, it will only incur cost for Amazon S3 and possibly for AWS Glue Data Catalog storage. When needed, this solution will scale out effortlessly.

Ready to get started? Read more and get started on building Amazon S3 Serverless file metadata search:

Creating AWS Serverless batch processing architectures

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/creating-aws-serverless-batch-processing-architectures/

This post is written by Reagan Rosario, AWS Solutions Architect and Mark Curtis, Solutions Architect, WWPS.

Batch processes are foundational to many organizations and can help process large amounts of information in an efficient and automated way. Use cases include file intake processes, queue-based processing, and transactional jobs, in addition to heavy data processing jobs.

This post explains a serverless solution for batch processing to implement a file intake process. This example uses AWS Step Functions for orchestration, AWS Lambda functions for on-demand instance compute, Amazon S3 for storing the data, and Amazon SES for sending emails.

Overview

This post’s example takes a common use-case of a business’s need to process data uploaded as a file. The test file has various data fields such as item ID, order date, order location. The data must be validated, processed, and enriched with related information such as unit price. Lastly, this enriched data may need to be sent to a third-party system.

Step Functions allows you to coordinate multiple AWS services in fully managed workflows to build and update applications quickly. You can also create larger workflows out of smaller workflows by using nesting. This post’s architecture creates a smaller and modular Chunk processor workflow, which is better for processing smaller files.

As the file size increases, the size of the payload passed between states increases. Executions that pass large payloads of data between states can be stopped if they exceed the maximum payload size of 262,144 bytes.

To process large files and to make the workflow modular, I split the processing between two workflows. One workflow is responsible for splitting up a larger file into chunks. A second nested workflow is responsible for processing records in individual chunk files. This separation of high-level workflow steps from low-level workflow steps also allows for easier monitoring and debugging.

Splitting the files in multiple chunks can also improve performance by processing each chunk in parallel. You can further improve the performance by using dynamic parallelism via the map state for each chunk.

Solution architecture

  1. The file upload to an S3 bucket triggers the S3 event notification. It invokes the Lambda function asynchronously with an event that contains details about the object.
  2. Lambda function calls the Main batch orchestrator workflow to start the processing of the file.
  3. Main batch orchestrator workflow reads the input file and splits it into multiple chunks and stores them in an S3 bucket.
  4. Main batch orchestrator then invokes the Chunk Processor workflow for each split file chunk.
  5. Each Chunk processor workflow execution reads and processes a single split chunk file.
  6. Chunk processor workflow writes the processed chunk file back to the S3 bucket.
  7. Chunk processor workflow writes the details about any validation errors in an Amazon DynamoDB table.
  8. Main batch orchestrator workflow then merges all the processed chunk files and saves it to an S3 bucket.
  9. Main batch orchestrator workflow then emails the consolidated files to the intended recipients using Amazon Simple Email Service.

Step Functions workflow

  1. The Main batch orchestrator workflow orchestrates the processing of the file.
    1. The first task state Split Input File into chunks calls a Lambda function. It splits the main file into multiple chunks based on the number of records and stores each chunk into an S3 bucket.
    2. The next task state Call Step Functions for each chunk invokes a Lambda function. It triggers a workflow for each chunk of the file. It passes information such as the name of bucket and the key where the chunk file to be processed is present.
    3. Then we wait for all the child workflow executions to complete.
    4. Once all the child workflows are processed successfully, the next task state is Merge all Files. This combines all the processed chunks into a single file and then stores the file back to the S3 bucket.
    5. The next task state Email the file takes the output file. It generates an S3 presigned URL for the file and sends an email with the S3 presigned URL.Chunk processor workflow
  2. The Chunk processor workflow is responsible for processing each row from the chunk file that was passed.
    1. The first task state Read reads the chunked file from S3 and converts it to an array of JSON objects. Each JSON object represents a row in the chunk file.
    2. The next state is a map state called Process messages (not shown in the preceding visual workflow). It runs a set of steps for each element of an input array. The input to the map state is an array of JSON objects passed by the previous task.
    3. Within the map state, Validate Data is the first state. It invokes a Lambda function that validates each JSON object using the rules that you have created. Records that fail validation are stored in an Amazon DynamoDB table.
    4. The next state Get Financial Data invokes Amazon API Gateway endpoints to enrich the data in the file with data from a DynamoDB table.
    5. When the map state iterations are complete, the Write output file state triggers a task. It calls a Lambda function, which converts the JSON data back to CSV and writes the output object to S3.

Prerequisites

Deploying the application

  1. Clone the repository.
  2. Change to the directory and build the application source:
    sam build
    sam build
  3. Package and deploy the application to AWS. When prompted, input the corresponding parameters as shown below:
    sam deploy –guided
    sam deployNote the template parameters:
    • SESSender: The sender email address for the output file email.
    • SESRecipient: The recipient email address for the output file email.
    • SESIdentityName: An email address or domain that Amazon SES users use to send email.
    • InputArchiveFolder: Amazon S3 folder where the input file will be archived after processing.
    • FileChunkSize: Size of each of the chunks, which is split from the input file.
    • FileDelimiter: Delimiter of the CSV file (for example, a comma).
  4. After the stack creation is complete, you see the source bucket created in Outputs.
    Outputs
  5. Review the deployed components in the AWS CloudFormation Console.
    CloudFormation console

Testing the solution

  1. Before you can send an email using Amazon SES, you must verify each identity that you’re going to use as a “From”, “Source”, “Sender”, or “Return-Path” address to prove that you own it. Refer Verifying identities in Amazon SES for more information.
  2. Locate the S3 bucket (SourceBucket) in the Resources section of the CloudFormation stack. Choose the physical ID.
    s3 bucket ID
  3. In the S3 console for the SourceBucket, choose Create folder. Name the folder input and choose Create folder.
    Create folder
  4. The S3 event notification on the SourceBucket uses “input” as the prefix and “csv” as the suffix. This triggers the notification Lambda function. This is created as a part of the custom resource in the AWS SAM template.
    Event notification
  5. In the S3 console for the SourceBucket, choose the Upload button. Choose Add files and browse to the input file (testfile.csv). Choose Upload.
    Upload dialog
  6. Review the data in the input file testfile.csv.
    Testfile.csv
  7. After the object is uploaded, the event notification triggers the Lambda Function. This starts the main orchestrator workflow. In the Step Functions console, you see the workflow is in a running state.
    Step Functions console
  8. Choose an individual state machine to see additional information.
    State machine
  9. After a few minutes, both BlogBatchMainOrchestrator and BlogBatchProcessChunk workflows have completed all executions. There is one execution for the BlogBatchMainOrchestrator workflow and multiple invocations of the BlogBatchProcessChunk workflow. This is because the BlogBatchMainOrchestrator invokes the BlogBatchProcessChunk for each of the chunked files.
    Workflow #1Workflow #2

Checking the output

  1. Open the S3 console and verify the folders created after the process has completed.
    S3 folders
    The following subfolders are created after the processing is complete:
    – input_archive – Folder for archival of the input object.
    – 0a47ede5-4f9a-485e-874c-7ff19d8cadc5 – Subfolder with a unique UUID in the name. This is created for storing the objects generated during batch execution.
  2. Select the folder 0a47ede5-4f9a-485e-874c-7ff19d8cadc5.
    Folder contents
    output – This folder contains the completed output objects, some housekeeping files, and processed chunk objects.
    Output folderto_process – This folder contains all the split objects from the original input file.
    to_process folder
  3. Open the processed object from the output/completed folder.
    Processed object
    Inspect the output object testfile.csv. It is enriched with additional data (columns I through N) from the DynamoDB table fetched through an API call.Output testfile.csv

Viewing a completed workflow

Open the Step Functions console and browse to the BlogBatchMainOrchestrator and BlogBatchProcessChunk state machines. Choose one of the executions of each to locate the Graph Inspector. This shows the execution results for each state.

BlogBatchMainOrchestrator:

BlogBatchMainOrchestrator

BlogBatchProcessChunk:

BlogBatchProcessChunk

Batch performance

For this use case, this is the time taken for the batch to complete, based on the number of input records:

No. of records Time for batch completion
10 k 5 minutes
100 k 7 minutes

The performance of the batch depends on other factors such as the Lambda memory settings and data in the file. Read more about Profiling functions with AWS Lambda Power Tuning.

Conclusion

This blog post shows how to use Step Functions’ features and integrations to orchestrate a batch processing solution. You use two Steps Functions workflows to implement batch processing, with one workflow splitting the original file and a second workflow processing each chunk file.

The overall performance of our batch processing application is improved by splitting the input file into multiple chunks. Each chunk is processed by a separate state machine. Map states further improve the performance and efficiency of workflows by processing individual rows in parallel.

Download the code from this repository to start building a serverless batch processing system.

Additional Resources:

For more serverless learning resources, visit Serverless Land.

Backwards-compatibility in Cloudflare Workers

Post Syndicated from Kenton Varda original https://blog.cloudflare.com/backwards-compatibility-in-cloudflare-workers/

Backwards-compatibility in
Cloudflare Workers

Backwards-compatibility in
Cloudflare Workers

Cloudflare Workers is our serverless platform that runs your code in 250+ cities worldwide.

On the Workers team, we have a policy:

A change to the Workers Runtime must never break an application that is live in production.

It seems obvious enough, but this policy has deep consequences. What if our API has a bug, and some deployed Workers accidentally depend on that bug? Then, seemingly, we can’t fix the bug! That sounds… bad?

This post will dig deeper into our policy, explaining why Workers is different from traditional server stacks in this respect, and how we’re now making backwards-incompatible changes possible by introducing “compatibility dates”.

TL;DR: Developers may now opt into backwards-incompatible fixes by setting a compatibility date.

Serverless demands strict compatibility

Workers is a serverless platform, which means we maintain the server stack for you. You do not have to manage the runtime version, you only manage your own code. This means that when we update the Workers Runtime, we update it for everyone. We do this at least once a week, sometimes more.

This means that if a runtime upgrade breaks someone’s application, it’s really bad. The developer didn’t make any change, so won’t be watching for problems. They may be asleep, or on vacation. If we want people to trust serverless, we can’t let this happen.

This is very different from traditional server platforms, where the developer maintains their own stack. For example, when a developer maintains a traditional VM-based server running Node.js applications, then the developer must decide exactly when to upgrade to a new version of Node.js. Careful developers do not upgrade Node.js 14 to Node.js 16 in production without testing first. They typically verify that their application works in a staging environment before going to production. A developer who doesn’t have time to spend testing each new version may instead choose to rely on a long-term support release, applying only low-risk security patches.

In the old world, if the Node.js maintainers decide to make a breaking change to an obscure API between releases, it’s OK. Downstream developers are expected to test their code before upgrading, and address any breakages. But in the serverless world, it’s not OK: developers have no control over when upgrades happen, therefore upgrades must never break anything.

But sometimes we need to fix things

Sometimes, we get things wrong, and we need to fix them. But sometimes, the fix would break people.

For example, in Workers, the fetch() function is used to make outgoing HTTP requests. Unfortunately, due to an oversight, our original implementation of fetch(), when given a non-HTTP URL, would silently interpret it as HTTP instead. For example, if you did fetch(“ftp://example.com”), you’d get the same result as fetch(“http://example.com”).

This is obviously not what we want and could lead to confusion or deeper bugs. Instead, fetch() should throw an exception in these cases. However, we couldn’t simply fix the problem, because a surprising number of live Workers depended on the behavior. For whatever reason, some Workers fetch FTP URLs and expect to get a result back. Perhaps they are fetching from sites that support both FTP and HTTP, and they arbitrarily chose FTP and it worked. Perhaps the fetches aren’t actually working, but changing a 404 error result into an exception would break things worse. When you have tens of thousands of new developers deploying applications every month, inevitably there’s always someone relying on any bug. We can’t “fix” the bug because it would break these applications.

The obvious solutions don’t work

Could we contact developers and ask them to fix their code?

No, because the problem is our fault, not the application developer’s, and the developer may not have time to help us fix our problems.

The fact that a Worker is doing something “wrong” — like using an FTP URL when they should be using HTTP — doesn’t necessarily mean the developer did anything wrong. Everyone writes code with bugs. Good developers rely on careful testing to make sure their code does what it is supposed to.

But what if the test only worked because of a bug in the underlying platform that caused it to do the right thing by accident? Well, that’s the platform’s fault. The developer did everything they could: they tested their code thoroughly, and it worked.

Developers are busy people. Nobody likes hearing that they need to drop whatever they are doing to fix a problem in code that they thought worked — especially code that has been working fine for years without anyone touching it. We think developers have enough on their plates already, we shouldn’t be adding more work.

Could we run multiple versions of the Workers Runtime?

No, for three reasons.

First, in order for edge computing to be effective, we need to be able to host a very large number of applications in each instance of the Workers Runtime. This is what allows us to run your code in hundreds of locations around the world at minimal cost. If we ran a separate copy of the runtime for each application, we’d need to charge a lot more, or deploy your code to far fewer locations. So, realistically it is infeasible for us to have different Workers asking for different versions of the runtime.

Second, part of the promise of serverless is that developers shouldn’t have to worry about updating their stack. If we start letting people pin old versions, then we have to start telling people how long they are allowed to do so, alerting people about security updates, giving people documentation that differentiates versions, and so on. We don’t want developers to have to think about any of that.

Third, this doesn’t actually solve the real problem anyway. We can easily implement multiple behaviors within the same runtime binary. But how do we know which behavior to use for any particular Worker?

Introducing Compatibility Dates

Going forward, every Worker is assigned a “compatibility date”, which must be a date in the past. The date is specified inside the project’s metadata (for Wrangler projects, in wrangler.toml). This metadata is passed to the Cloudflare API along with the application code whenever it is updated and deployed. A compatibility date typically starts out as the date when the Worker was first created, but can be updated from time to time.

# wrangler.toml
compatibility_date = "2021-09-20"

We can now introduce breaking changes. When we do, the Workers Runtime must implement both the old and the new behavior, and chooses behavior based on the compatibility date. Each time we introduce a new change, we choose a date in the future when that change will become the default. Workers with a later compatibility date will see the change; Workers with an older compatibility date will retain the old behavior.

A page in our documentation lists the history of breaking changes — and only breaking changes. When you wish to update your Worker’s compatibility date, you can refer to this page to quickly determine what might be affected, so that you can test for problems.

We will reserve the compatibility system strictly for changes which cannot be made without causing a breakage. We don’t want to force people to update their compatibility date to get regular updates, including new features, non-breaking bug fixes, and so on.

If you’d prefer never to update your compatibility date, that’s OK! Old compatibility dates are intended to be supported forever. However, if you are frequently updating your code, you should update your compatibility date along with it.

Acknowledgement

While the details are a bit different, we were inspired by Stripe’s API versioning, as well as the absolute promise of backwards compatibility maintained by both the Linux kernel system call API and the Web Platform implemented by browsers.

Operating serverless at scale: Keeping control of resources – Part 3

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/operating-serverless-at-scale-keeping-control-of-resources-part-3/

This post is written by Jerome Van Der Linden, Solutions Architect.

In the previous part of this series, I provide application archetypes for developers to follow company best practices and include libraries needed for compliance. But using these archetypes is optional and teams can still deploy resources without them. Even if they use them, the templates can be modified. Developers can remove a layer, over-permission functions, or allow access to APIs without appropriate authorization.

To avoid this, you must define guardrails. Templates are good for providing guidance, best practices and to improve productivity. But they do not prevent actions like guardrails do. There are two kinds of guardrails:

  • Proactive: you define rules and permissions that avoid some specific actions.
  • Reactive: you define controls that detect if something happens and trigger notifications to alert someone or remediate actions.

This third part on serverless governance describes different guardrails and ways to implement them.

Implementing proactive guardrails

Proactive guardrails are often the most efficient but also the most restrictive. Be sure to apply them with caution as you could reduce developers’ agility and productivity. For example, test in a sandbox account before applying more broadly.

In this category, you typically find IAM policies and service control policies. This section explores some examples applied to serverless applications.

Controlling access through policies

Part 2 discusses Lambda layers, to include standard components and ensure compliance of Lambda functions. You can enforce the use of a Lambda layer when creating or updating a function, using the following policy. The condition checks if a layer is configured with the appropriate layer ARN:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "ConfigureFunctions",
            "Effect": "Allow",
            "Action": [
                "lambda:CreateFunction",
                "lambda:UpdateFunctionConfiguration"
            ],
            "Resource": "*",
            "Condition": {
                "ForAllValues:StringLike": {
                    "lambda:Layer": [
                        "arn:aws:lambda:*:123456789012:layer:my-company-layer:*"
                    ]
                }
            }
        }
    ]
}

When deploying Lambda functions, some companies also want to control the source code integrity and verify it has not been altered. Using code signing for AWS Lambda, you can sign the package and verify its signature at deployment time. If the signature is not valid, you can be warned or even block the deployment.

An administrator must first create a signing profile (you can see it as a trusted publisher) using AWS Signer. Then, a developer can reference this profile in its AWS SAM template to sign the Lambda function code:

Resources:
  MyFunction:
    Type: AWS::Serverless::Function
    Properties:
      CodeUri: src/
      Handler: app.lambda_handler
      Runtime: python3.9
      CodeSigningConfigArn: !Ref MySignedFunctionCodeSigningConfig

  MySignedFunctionCodeSigningConfig:
    Type: AWS::Lambda::CodeSigningConfig
    Properties:
      AllowedPublishers:
        SigningProfileVersionArns:
          - arn:aws:signer:eu-central-1:123456789012:/signing-profiles/MySigningProfile
      CodeSigningPolicies:
        UntrustedArtifactOnDeployment: "Enforce"

Using the AWS SAM CLI and the --signing-profile option, you can package and deploy the Lambda function using the appropriate configuration. Read the documentation for more details.

You can also enforce the use of code signing by using a policy so that every function must be signed before deployment. Use the following policy and a condition requiring a CodeSigningConfigArn:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "ConfigureFunctions",
            "Effect": "Allow",
            "Action": [
                "lambda:CreateFunction"
            ],
            "Resource": "*",
            "Condition": {
                "StringEquals": {
                    "lambda:CodeSigningConfigArn": "arn:aws:lambda:eu-central-1:123456789012:code-signing-config:csc-0c44689353457652"
                }
            }
        }
    ]
}

When using Amazon API Gateway, you may want to use a standard authorization mechanism. For example, a Lambda authorizer to validate a JSON Web Token (JWT) issued by your company identity provider. You can do that using a policy like this:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DenyWithoutJWTLambdaAuthorizer",
      "Effect": "Deny",
      "Action": [
        "apigateway:PUT",
        "apigateway:POST",
        "apigateway:PATCH"
      ],
      "Resource": [
        "arn:aws:apigateway:eu-central-1::/apis",
        "arn:aws:apigateway:eu-central-1::/apis/??????????",
        "arn:aws:apigateway:eu-central-1::/apis/*/authorizers",
        "arn:aws:apigateway:eu-central-1::/apis/*/authorizers/*"
      ],
      "Condition": {
        "ForAllValues:StringNotEquals": {
          "apigateway:Request/AuthorizerUri": 
            "arn:aws:apigateway:eu-central-1:lambda:path/2015-03-31/functions/arn:aws:lambda:eu-central-1:123456789012:function:MyCompanyJWTAuthorizer/invocations"
        }
      }
    }
  ]
}

To enforce the use of mutual authentication (mTLS) and TLS version 1.2 for APIs, use the following policy:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceTLS12",
      "Effect": "Allow",
      "Action": [
        "apigateway:POST"
      ],
      "Resource": [
        "arn:aws:apigateway:eu-central-1::/domainnames",
        "arn:aws:apigateway:eu-central-1::/domainnames/*"
      ],
      "Condition": {
        "ForAllValues:StringEquals": {
            "apigateway:Request/SecurityPolicy": "TLS_1_2"
        }
      }
    }
  ]
}

You can apply other guardrails for Lambda, API Gateway, or another service. Read the available policies and conditions for your service here.

Securing self-service with permissions boundaries

When creating a Lambda function, developers must create a role that the function will assume when running. But by giving the ability to create roles to developers, one could elevate their permission level. In the following diagram, you can see that an admin gives this ability to create roles to developers:

Securing self-service with permissions boundaries

Developer 1 creates a role for a function. This only allows Amazon DynamoDB read/write access and a basic execution role for Lambda (for Amazon CloudWatch Logs). But developer 2 is creating a role with administrator permission. Developer 2 cannot assume this role but can pass it to the Lambda function. This role could be used to create resources on Amazon EC2, delete an Amazon RDS database or an Amazon S3 bucket, for example.

To avoid users elevating their permissions, define permissions boundaries. With these, you can limit the scope of a Lambda function’s permissions. In this example, an admin still gives the same ability to developers to create roles but this time with a permissions boundary attached. Now the function cannot perform actions that exceed this boundary:

Effect of permissions boundaries

The admin must first define the permissions boundaries within an IAM policy:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "LambdaDeveloperBoundary",
            "Effect": "Allow",
            "Action": [
                "s3:List*",
                "s3:Get*",
                "logs:*",
                "dynamodb:*",
                "lambda:*"
            ],
            "Resource": "*"
        }
    ]
}

Note that this boundary is still too permissive and you should reduce and adopt a least privilege approach. For example, you may not want to grant the dynamodb:DeleteTable permission or restrict it to a specific table.

The admin can then provide the CreateRole permission with this boundary using a condition:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "CreateRole",
            "Effect": "Allow",
            "Action": [
                "iam:CreateRole"
            ],
            "Resource": "arn:aws:iam::123456789012:role/lambdaDev*",
            "Condition": {
                "StringEquals": {
                    "iam:PermissionsBoundary": "arn:aws:iam::123456789012:policy/lambda-dev-boundary"
                }
            }
        }
    ]
}

Developers assuming a role lambdaDev* can create a role for their Lambda functions but these functions cannot have more permissions than defined in the boundary.

Deploying reactive guardrails

The principle of least privilege is not always easy to accomplish. To achieve it without this permission management burden, you can use reactive guardrails. Actions are allowed but they are detected and trigger a notification or a remediation action.

To accomplish this on AWS, use AWS Config. It continuously monitors your resources and their configurations. It assesses them against compliance rules that you define and can notify you or automatically remediate to non-compliant resources.

AWS Config has more than 190 built-in rules and some are related to serverless services. For example, you can verify that an API Gateway REST API is configured with SSL or protected by a web application firewall (AWS WAF). You can ensure that a DynamoDB table has back up configured in AWS Backup or that data is encrypted.

Lambda also has a set of rules. For example, you can ensure that functions have a concurrency limit configured, which you should. Most of these rules are part of the “Operational Best Practices for Serverless” conformance pack to ease their deployment as a single entity. Otherwise, setting rules and remediation can be done in the AWS Management Console or AWS CLI.

If you cannot find a rule for your use case in the AWS Managed Rules, you can find additional ones on GitHub or write your own using the Rule Development Kit (RDK). For example, enforcing the use of a Lambda layer for functions. This is possible using a service control policy but it denies the creation or modification of the function if the layer is not provided. You can use this policy in production but you may only want to notify the developers in their sandbox accounts or test environments.

By using the RDK CLI, you can bootstrap a new rule:

rdk create LAMBDA_LAYER_CHECK --runtime python3.9 \
--resource-types AWS::Lambda::Function \
--input-parameters '{"LayerArn":"arn:aws:lambda:region:account:layer:layer_name", "MinLayerVersion":"1"}'

It generates a Lambda function, some tests, and a parameters.json file that contains the configuration for the rule. You can then edit the Lambda function code and the evaluate_compliance method. To check for a layer:

LAYER_REGEXP = 'arn:aws:lambda:[a-z]{2}((-gov)|(-iso(b?)))?-[a-z]+-\d{1}:\d{12}:layer:[a-zA-Z0-9-_]+'

def evaluate_compliance(event, configuration_item, valid_rule_parameters):
    pkg = configuration_item['configuration']['packageType']
    if not pkg or pkg != "Zip":
        return build_evaluation_from_config_item(configuration_item, 'NOT_APPLICABLE',
                                                 annotation='Layers can only be used with functions using Zip package type')

    layers = configuration_item['configuration']['layers']
    if not layers:
        return build_evaluation_from_config_item(configuration_item, 'NON_COMPLIANT',
                                                 annotation='No layer is configured for this Lambda function')

    regex = re.compile(LAYER_REGEXP + ':(.*)')
    annotation = 'Layer ' + valid_rule_parameters['LayerArn'] + ' not used for this Lambda function'
    for layer in layers:
        arn = layer['arn']
        version = regex.search(arn).group(5)
        arn = re.sub('\:' + version + '$', '', arn)
        if arn == valid_rule_parameters['LayerArn']:
            if version >= valid_rule_parameters['MinLayerVersion']:
                return build_evaluation_from_config_item(configuration_item, 'COMPLIANT')
            else:
                annotation = 'Wrong layer version (was ' + version + ', expected ' + valid_rule_parameters['MinLayerVersion'] + '+)'

    return build_evaluation_from_config_item(configuration_item, 'NON_COMPLIANT',
                                             annotation=annotation)

You can find the complete source of this AWS Config rule and its tests on GitHub.

Once the rule is ready, use the command rdk deploy to deploy it on your account. To deploy it across multiple accounts, see the documentation. You can then define remediation actions. For example, automatically add the missing layer to the function or send a notification to the developers using Amazon Simple Notification Service (SNS).

Conclusion

This post describes guardrails that you can set up in your accounts or across the organization to keep control over deployed resources. These guardrails can be more or less restrictive according to your requirements.

Use proactive guardrails with service control policies to define coarse-grained permissions and block everything that must not be used. Define reactive guardrails for everything else to aid agility and productivity but still be informed of the activity and potentially remediate.

This concludes this series on serverless governance:

  • Standardization is an important aspect of the governance to speed up teams and ensure that deployed applications are operable and compliant with your internal rules. Use templates, layers, and other mechanisms to create shareable archetypes to apply these standards and rules at the enterprise level.
  • It’s important to keep visibility and control on your resources, to understand how your environment evolves and to be able to operate and act if needed. Tags and guardrails are helpful to achieve this and they should evolve as your maturity with the cloud evolves.

Find more SCP examples and all the AWS managed AWS Config rules in the documentation.

For more serverless learning resources, visit Serverless Land.

Building dynamic Amazon SNS subscriptions for auto scaling container workloads 

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/building-dynamic-amazon-sns-subscriptions-for-auto-scaling-container-workloads/

This post is written by Mithun Mallick, Senior Specialist Solutions Architect, App Integration.

Amazon Simple Notification Service (SNS) is a serverless publish subscribe messaging service. It supports a push-based subscriptions model where subscribers must register an endpoint to receive messages. Amazon Simple Queue Service (SQS) is one such endpoint, which is used by applications to receive messages published on an SNS topic.

With containerized applications, the container instances poll the queue and receive the messages. However, containerized applications can scale out for a variety of reasons. The creation of an SQS queue for each new container instance creates maintenance overhead for customers. You must also clean up the SNS-SQS subscription once the instance scales in.

This blog walks through a dynamic subscription solution, which automates the creation, subscription, and deletion of SQS queues for an Auto Scaling group of containers running in Amazon Elastic Container Service (ECS).

Overview

The solution is based on the use of events to achieve the dynamic subscription pattern. ECS uses the concept of tasks to create an instance of a container. You can find more details on ECS tasks in the ECS documentation.

This solution uses the events generated by ECS to manage the complete lifecycle of an SNS-SQS subscription. It uses the task ID as the name of the queue that is used by the ECS instance for pulling messages. More details on the ECS task ID can be found in the task documentation.

This also uses Amazon EventBridge to apply rules on ECS events and trigger an AWS Lambda function. The first rule detects the running state of an ECS task and triggers a Lambda function, which creates the SQS queue with the task ID as queue name. It also grants permission to the queue and creates the SNS subscription on the topic.

As the container instance starts up, it can send a request to its metadata URL and retrieve the task ID. The task ID is used by the container instance to poll for messages. If the container instance terminates, ECS generates a task stopped event. This event matches a rule in Amazon EventBridge and triggers a Lambda function. The Lambda function retrieves the task ID, deletes the queue, and deletes the subscription from the SNS topic. The solution decouples the container instance from any overhead in maintaining queues, applying permissions, or managing subscriptions. The security permissions for all SNS-SQS management are handled by the Lambda functions.

This diagram shows the solution architecture:

Solution architecture

Events from ECS are sent to the default event bus. There are various events that are generated as part of the lifecycle of an ECS task. You can find more on the various ECS task states in ECS task documentation. This solution uses ECS as the container orchestration service but you can also use Amazon Elastic Kubernetes Service.(EKS). For EKS, you must apply the rules for EKS task state events.

Walkthrough of the implementation

The code snippets are shortened for brevity. The full source code of the solution is in the GitHub repository. The solution uses AWS Serverless Application Model (AWS SAM) for deployment.

SNS topic

The SNS topic is used to send notifications to the ECS tasks. The following snippet from the AWS SAM template shows the definition of the SNS topic:

  SNSDynamicSubsTopic:
    Type: AWS::SNS::Topic
    Properties:
      TopicName: !Ref DynamicSubTopicName

Container instance

The container instance subscribes to the SNS topic using an SQS queue. The container image is a Java class that reads messages from an SQS queue and prints them in the logs. The following code shows some of the message processor implementation:

AmazonSQS sqs = AmazonSQSClientBuilder.defaultClient();
AmazonSQSResponder responder = AmazonSQSResponderClientBuilder.standard()
        .withAmazonSQS(sqs)
        .build();

SQSMessageConsumer consumer = SQSMessageConsumerBuilder.standard()
        .withAmazonSQS(responder.getAmazonSQS())
        .withQueueUrl(queue_url)
        .withConsumer(message -> {
            System.out.println("The message is " + message.getBody());
            sqs.deleteMessage(queue_url,message.getReceiptHandle());

        }).build();
consumer.start();

The queue_url highlighted is the task ID of the ECS task. It is retrieved in the constructor of the class:

String metaDataURL = map.get("ECS_CONTAINER_METADATA_URI_V4");

HttpGet request = new HttpGet(metaDataURL);
CloseableHttpResponse response = httpClient.execute(request);

HttpEntity entity = response.getEntity();
if (entity != null) {
    String result = EntityUtils.toString(entity);
    String taskARN = JsonPath.read(result, "$['Labels']['com.amazonaws.ecs.task-arn']").toString();
    String[] arnTokens = taskARN.split("/");
    taskId = arnTokens[arnTokens.length-1];
    System.out.println("The task arn : "+taskId);
}

queue_url = sqs.getQueueUrl(taskId).getQueueUrl();

The queue URL is constructed from the task ID of the container. Each queue is dedicated to each of the tasks or the instances of the container running in ECS.

EventBridge rules

The following event pattern on the default event bus captures events that match the start of the container instance. The rule triggers a Lambda function:

      EventPattern:
        source:
          - aws.ecs
        detail-type:
          - "ECS Task State Change"
        detail:
          desiredStatus:
            - "RUNNING"
          lastStatus:  
            - "RUNNING"

The start rule routes events to a Lambda function that creates a queue with the name as the task ID. It creates the subscription to the SNS topic and grants permission on the queue to receive messages from the topic.

This event pattern matches STOPPED events of the container task. It also triggers a Lambda function to delete the queue and the associated subscription:

      EventPattern:
        source:
          - aws.ecs
        detail-type:
          - "ECS Task State Change"
        detail:
          desiredStatus:
            - "STOPPED"
          lastStatus:  
            - "STOPPED"

Lambda functions

There are two Lambda functions that perform the queue creation, subscription, authorization, and deletion.

The SNS-SQS-Subscription-Service

The following code creates the queue based on the task id, applies policies, and subscribes it to the topic. It also stores the subscription ARN in a Amazon DynamoDB table:

# get the task id from the event
taskArn = event['detail']['taskArn']
taskArnTokens = taskArn.split('/')
taskId = taskArnTokens[len(taskArnTokens)-1]

create_queue_resp = sqs_client.create_queue(QueueName=queue_name)

response = sns.subscribe(TopicArn=topic_arn, Protocol="sqs", Endpoint=queue_arn)

ddbresponse = dynamodb.update_item(
    TableName=SQS_CONTAINER_MAPPING_TABLE,
    Key={
        'id': {
            'S' : taskId.strip()
        }
    },
    AttributeUpdates={
        'SubscriptionArn':{
            'Value': {
                'S': subscription_arn
            }
        }
    },
    ReturnValues="UPDATED_NEW"
)

The cleanup service

The cleanup function is triggered when the container instance is stopped. It fetches the subscription ARN from the DynamoDB table based on the taskId. It deletes the subscription from the topic and deletes the queue. You can modify this code to include any other cleanup actions or trigger a workflow. The main part of the function code is:

taskId = taskArnTokens[len(taskArnTokens)-1]

ddbresponse = dynamodb.get_item(TableName=SQS_CONTAINER_MAPPING_TABLE,Key={'id': { 'S' : taskId}})
snsresp = sns.unsubscribe(SubscriptionArn=subscription_arn)

queuedelresp = sqs_client.delete_queue(QueueUrl=queue_url)

Conclusion

This blog shows an event driven approach to handling dynamic SNS subscription requirements. It relies on the ECS service events to trigger appropriate Lambda functions. These create the subscription queue, subscribe it to a topic, and delete it once the container instance is terminated.

The approach also allows the container application logic to focus only on consuming and processing the messages from the queue. It does not need any additional permissions to subscribe or unsubscribe from the topic or apply any additional permissions on the queue. Although the solution has been presented using ECS as the container orchestration service, it can be applied for EKS by using its service events.

For more serverless learning resources, visit Serverless Land.

Visualizing AWS Step Functions workflows from the AWS Batch console

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/visualizing-aws-step-functions-workflows-from-the-aws-batch-console/

This post written by Dhiraj Mahapatro, Senior Specialist SA, Serverless.

AWS Step Functions is a low-code visual workflow service used to orchestrate AWS services, automate business processes, and build serverless applications. Step Functions workflows manage failures, retries, parallelization, service integrations, and observability so builders can focus on business logic.

AWS Batch is one of the service integrations that are available for Step Functions. AWS Batch enables users to more easily and efficiently run hundreds of thousands of batch computing jobs on AWS. AWS Batch dynamically provisions the optimal quantity and compute resource classifications based on the volume and specific resource requirements of the batch jobs submitted. AWS Batch plans, schedules, and runs batch computing workloads across the full range of AWS compute services and features, such as AWS Fargate, Amazon EC2, and spot instances.

Now, Step Functions is available to AWS Batch users through the AWS Batch console. This feature enables AWS Batch users to augment compute options and have additional orchestration capabilities to manage their batch jobs.

This blog walks through Step Functions integration in AWS Batch console and shows how AWS Batch users can efficiently use Step Functions workflow orchestrators in batch workloads. A sample application also highlights the use of AWS Lambda as a compute option for AWS Batch.

Introducing workflow orchestration in AWS Batch console

Today, AWS users use AWS Batch for high performance computing, post-trade analytics, fraud surveillance, screening, DNA sequencing, and more. AWS Batch minimizes human error, increases speed and accuracy, and reduces costs with automation so that users can refocus on evolving the business.

In addition to using compute-intensive tasks, users sometimes need Lambda for simpler, less intense processing. Users also want to combine the two in a single business process that is scalable and repeatable.

Workflow orchestration (powered by Step Functions) in AWS Batch console allows orchestration of batch jobs with Step Functions state machine:

Workflow orchestration in Batch console

Workflow orchestration in Batch console

Using batch-related patterns from Step Functions

Error handling

Step Functions natively handles errors and retries of its workflows. Users rely on this native error handling mechanism to focus on building business logic.

Workflow orchestration in AWS Batch console provides common batch-related patterns that are present in Step Functions. Handling errors while submitting batch jobs in Step Functions is one of them.

Getting started with orchestration in Batch

Getting started with orchestration in Batch

  1. Choose Get Started from Handle complex errors.
  2. From the pop-up, choose Start from a template and choose Continue.

A new browser tab opens with Step Functions Workflow Studio. The Workflow Studio designer has a workflow pattern template pre-created. Diving deeper into the workflow highlights that the Step Functions workflow submits a batch job and then handles success and error scenarios by sending Amazon SNS notifications, respectively.

Alternatively, choosing Deploy a sample project from the Get Started pop-up deploys a sample Step Functions workflow.

Deploying a sample project

Deploying a sample project

This option allows creating a state machine from scratch, reviewing the workflow definition, deploying an AWS CloudFormation stack, and running the workflow in Step Functions console.

Deploy and run from console

Deploy and run from console

Once deployed, the state machine is visible in the Step Functions console as:

Viewing the state machine in the AWS Step Functions console

Viewing the state machine in the AWS Step Functions console

Select the BatchJobNotificationStateMachine to land on the details page:

View the state machine's details

View the state machine’s details

The CloudFormation template has already provisioned the required batch job in AWS Batch and the SNS topic for success and failure notification.

To see the Step Functions workflow in action, use Start execution. Keep the optional name and input as is and choose Start execution:

Run the Step Function

Run the Step Function

The state machine completes the tasks successfully by Submitting Batch Job using AWS Batch and Notifying Success using the SNS topic:

The successful results in the console

The successful results in the console

The state machine used the AWS Batch Submit Job task. The Workflow orchestration in AWS Batch console now highlights this newly created Step Functions state machine:

The state machine is listed in the Batch console

The state machine is listed in the Batch console

Therefore, any state machine that uses this task in Step Functions for this account is listed here as a state machine that orchestrates batch jobs.

Combine Batch and Lambda

Another pattern to use in Step Functions is the combination of Lambda and batch job.

Select Get Started from Combine Batch and Lambda pop-up followed by Start from a template and Continue. This takes the user to Step Functions Workflow studio with the following pattern. The Lambda task generates input for the subsequent batch job task. Submit Batch Job task takes the input and submits the batch job:

Combining AWS Lambda with AWS Step Functions

Combining AWS Lambda with AWS Step Functions

Step Functions enables AWS Batch users to combine Batch and Lambda functions to optimize compute spend while using the power of the different compute choices.

Fan out to multiple Batch jobs

In addition to error handling and combining Lambda with AWS Batch jobs, a user can fan out multiple batch jobs using Step Functions’ map state. Map state in Step Functions provides dynamic parallelism.

With dynamic parallelism, a user can submit multiple batch jobs based on a collection of batch job input data. With visibility to each iteration’s input and output, users can easily navigate and troubleshoot in case of failure.

Easily navigate and troubleshoot in case of failure

Easily navigate and troubleshoot in case of failure

AWS Batch users are not limited to the previous three patterns shown in Workflow orchestration in the AWS Batch console. AWS Batch users can start from scratch and build Step Functions state machine by navigating to the bottom right and using Create state machine:

Create a state machine from the Step Functions console

Create a state machine from the Step Functions console

Create State Machine in AWS Batch console opens a new tab with Step Functions console’s Create state machine page.

Design a workflow visually

Design a workflow visually

Refer building a state machine AWS Step Functions Workflow Studio for additional details.

Deploying the application

The sample application shows fan out to multiple batch jobs pattern. Before deploying the application, you need:

To deploy:

  1. From a terminal window, clone the GitHub repo:
    git clone [email protected]:aws-samples/serverless-batch-job-workflow.git
  2. Change directory:
    cd ./serverless-batch-job-workflow
  3. Download and install dependencies:
    sam build
  4. Deploy the application to your AWS account:
    sam deploy --guided

To run the application using the AWS CLI, replace the state machine ARN from the output of deployment steps:

aws stepfunctions start-execution \
    --state-machine-arn <StepFunctionArnHere> \
    --region <RegionWhereApplicationDeployed> \
    --input "{}"

Step Functions is not limited to AWS Batch’s Submit Job API action

In September 2021, Step Functions announced integration support for 200 AWS Services to enable easier workflow automation. With this announcement, Step Functions is not limited to integrate with AWS Batch’s SubmitJob API but also can integrate with any AWS Batch SDK API today.

Step Functions can automate the lifecycle of an AWS Batch job, starting from creating a compute environment, creating job queues, registering job definitions, submitting a job, and finally cleaning up.

Other AWS service integrations

Step Functions support for 200 AWS Services equates integration with more than 9,000 API actions across these services. AWS Batch tasks in Step Functions can evolve by integrating with available services in the workflow for their pre- and post-processing needs.

For example, batch job input data sanitization can be done inside Lambda and that gets pushed to an Amazon SQS queue or Amazon S3 as an object for auditability purposes.

Similarly, Amazon SNS, Amazon Pinpoint, or Amazon SES can notify once AWS Batch job task is complete.

There are multiple ways to decorate around an AWS Batch job task. Refer to AWS SDK service integrations and optimized integrations for Step Functions for additional details.

Important considerations

Workflow orchestrations in the AWS Batch console only show Step Functions state machines that use AWS Batch’s Submit Job task. Step Functions state machines do not show in the AWS Batch console when:

  1. A state machine uses any other AWS SDK Batch API integration task
  2. AWS Batch’s SubmitJob API is invoked inside a Lambda function task using an AWS SDK client (like Boto3 or Node.js or Java)

Cleanup

The sample application provisions AWS Batch (the job definition, job queue, and ECS compute environment inside a VPC). It also creates subnets, route tables, and an internet gateway. Clean up the stack after testing the application to avoid the ongoing cost of running these services.

To delete the sample application stack, use the latest version of AWS SAM CLI and run:

sam delete

Conclusion

To learn more on AWS Batch, read the Orchestrating Batch jobs section in the Batch developer guide.

To get started, open the workflow orchestration page in the Batch console. Select Orchestrate Batch jobs with Step Functions Workflows to deploy a sample project, if you are new to Step Functions.

This feature is available in all Regions where both Step Functions and AWS Batch are available. View the AWS Regions table for details.

To learn more on Step Functions patterns, visit Serverless Land.

Accepting API keys as a query string in Amazon API Gateway

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/accepting-api-keys-as-a-query-string-in-amazon-api-gateway/

This post was written by Ronan Prenty, Sr. Solutions Architect and Zac Burns, Cloud Support Engineer & API Gateway SME

Amazon API Gateway is a fully managed service that makes it easier for developers to create, publish, maintain, monitor, and secure APIs at any scale. APIs act as the front door to applications and allow developers to offload tasks like authorization, throttling, caching, and more.

A common feature requested by customers is the ability to track usage for specific users or services through API keys. API Gateway REST APIs support this feature and, for added security, require that the API key resides in a header or an authorizer.

Developers may also need to pass API keys in the query string parameters. Best practices encourage refactoring the requests at the client level to move API keys to the header. However, this may not be possible during the migration.

This blog explains how to build an API Gateway REST API that temporarily accepts API keys as query string parameters. This post helps customers who have APIs that accept API keys as query string parameters and want to migrate to API Gateway with minimal impact on their clients. The post also discusses increasing security by refactoring the client to send API keys as a header instead of a query string.

There is also an example project for you to test and evaluate. This solution uses a custom authorizer AWS Lambda function to extract the API key from the query string parameter and apply it to a usage plan. The sample application uses the AWS Serverless Application Model (AWS SAM) for deployment.

Key concepts

API keys and usage plans

API keys are alphanumeric strings that are distributed to developers to grant access to an API. API Gateway can generate these on your behalf, or you can import them.

Usage plans let you provide API keys to your customers so that you can track and limit their usage. API keys are not a primary authorization mechanism for your APIs. If multiple APIs are associated with a usage plan, a user with a valid API key can access all APIs in that usage plan. We provide numerous options for securing access to your APIs, including resource policies, Lambda authorizers, and Amazon Cognito user pools.

Usage plans define who can access deployed API stages and methods along with metering their usage. Usage plans use API keys to identify who is making requests and apply throttling and quota limits.

How API Gateway handles API keys

API Gateway supports API keys sent as headers in a request. It does not support API keys sent as a query string parameter. API Gateway only accepts requests over HTTPS, which means that the request is encrypted. When sending API keys as query string parameters, there is still a risk that URLs are logged in plaintext by the client sending requests.

API Gateway has two settings to accept API keys:

  1. Header: The request contains the values as the X-API-Key header. API Gateway then validates the key against a usage plan.
  2. Authorizer: The authorizer includes the API key as part of the authorization response. Once API Gateway receives the API key as part of the response, it validates it against a usage plan.

Solution overview

To accept an API key as a query string parameter temporarily, create a custom authorizer using a Lambda function:

Note: the apiKeySource property of your API must be set to Authorizer instead of Header.

Note: the apiKeySource property of your API must be set to Authorizer instead of Header.

  1. The client sends an HTTP request to the API Gateway endpoint with the API key in the query string.
  2. API Gateway sends the request to a REQUEST type custom authorizer
  3. The custom authorizer function extracts the API Key from the payload. It constructs the response object with the API Key as the value for the `usageIdentifierKey` property
  4. The response gets sent back to API Gateway for validation.
  5. API Gateway validates the API key against a usage plan.
  6. If valid, API Gateway passes the request to the backend.

Deploying the solution

Prerequisites

This solution requires no pre-existing AWS resources and deploys everything you need from the template. Deploying the solution requires:

You can find the solution on GitHub using this link.

With the prerequisites completed, deploy the template with the following commands:

git clone https://github.com/aws-samples/amazon-apigateway-accept-apikeys-as-querystring.git
cd amazon-apigateway-accept-apikeys-as-querystring
sam build --use-container
sam deploy --guided

Long term considerations

This temporary solution enables developers to migrate APIs to API Gateway and maintain query string-based API keys. While this solution does work, it does not follow best practices.

In addition to security, there is also a cost factor. Each time the client request contains an API key, the custom authorizer AWS Lambda function will be invoked, increasing the total amount of Lambda invocations you are billed for. To ensure you are billed only for valid requests, you can add an identity source to the custom authorizer meaning that only requests containing this identity source will be sent to the Lambda function. Requests that do not contain this identity source will not be billed by Lambda or API Gateway. Migrating to a header-based API key removes the need for a custom authorizer and the extra Lambda function invocations. You can find out more information on AWS Lambda billing here.

Customer migration process

With this in mind, the structure of the request sent by API clients must change from:

GET /some-endpoint?apiKey=abc123456789

To:

GET /some-endpoint
x-api-key: abc123456789

You can provide clients with a notice period when this temporary solution is operational. After, they must migrate to a new API endpoint using a header to provide the API keys. Once the client migration is complete, they can retire the custom solution.

Developer portal

In addition to migrating API keys to a header-based solution, customers also ask us how to manage customer keys and usage plans. One option is to deploy the API Gateway developer portal.

This portal enables your customers to discover available APIs, browse API documentation, register for API keys, test APIs in the user interface, and monitor their API usage. This portal also allows you to publish non-API Gateway managed APIs by uploading OpenAPI definitions. The serverless developer portal can be customized and branded to suit your organization.

Conclusion

This blog post demonstrates how to use custom authorizers in API Gateway to accept API keys as a query string parameter. It also provides an AWS SAM template to deploy an example application for testing. Finally, it discusses the importance of moving customers to header-based API keys and managing those keys with the developer portal.

For more serverless content, visit Serverless Land.
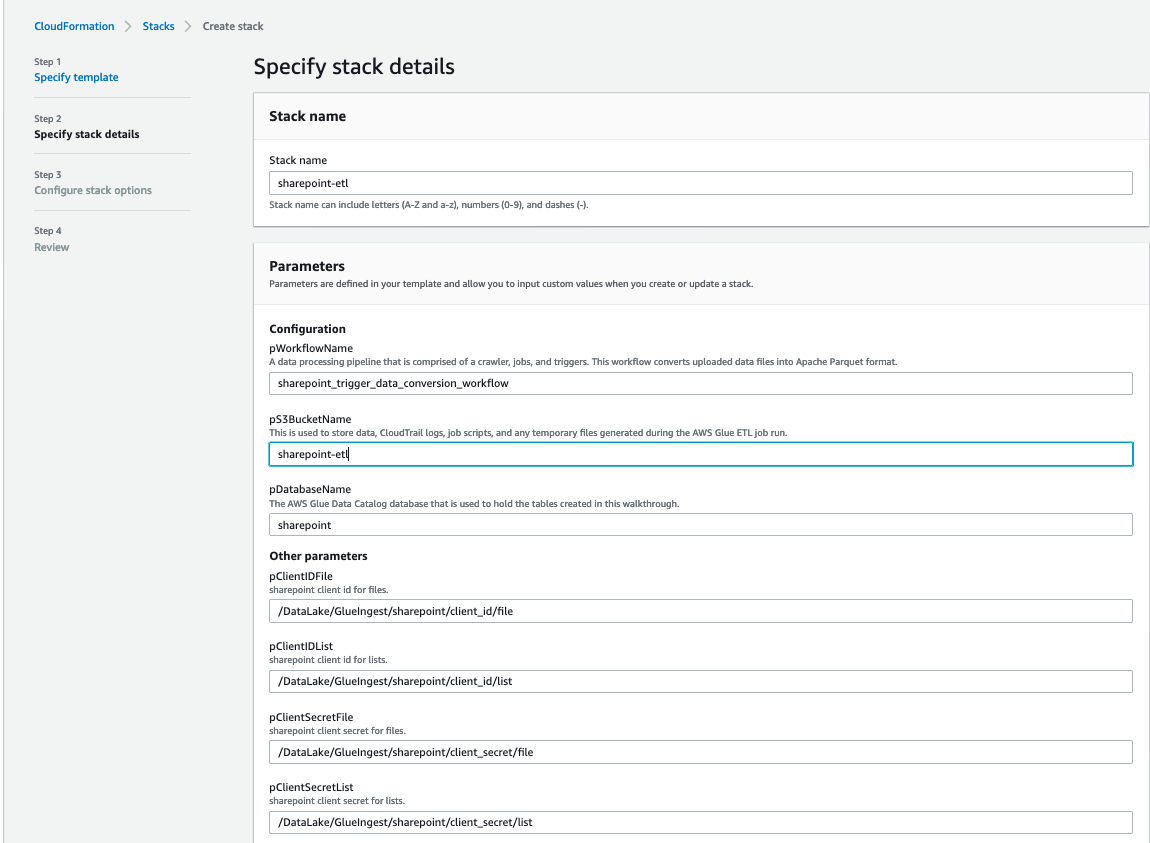
Using JSONPath effectively in AWS Step Functions

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/using-jsonpath-effectively-in-aws-step-functions/

This post is written by Dhiraj Mahapatro, Senior Serverless Specialist SA, Serverless.

AWS Step Functions uses Amazon States Language (ASL), which is a JSON-based, structured language used to define the state machine. ASL uses paths for input and output processing in between states. Paths follow JSONPath syntax.

JSONPath provides the capability to select parts of JSON structures similar to how XPath expressions select nodes of XML documents. Step Functions provides the data flow simulator, which helps in modeling input and output path processing using JSONPath.

This blog post explains how you can effectively use JSONPath in a Step Functions workflow. It shows how you can separate concerns between states by specifically identifying input to and output from each state. It also explains how you can use advanced JSONPath expressions for filtering and mapping JSON content.

Overview

The sample application in this blog is based on a use case in the insurance domain. A new potential customer signs up with an insurance company by creating an account. The customer provides their basic information, and their interests in the types of insurances for shopping later.

The information provided by the potential insurance customer is accepted by the insurance company’s new account application for processing. This application is built using Step Functions, which accepts provided input as a JSON payload and applies the following business logic:

Example application architecture

  1. Verify the identity of the user.
  2. Verify the address of the user.
  3. Approve the new account application if the checks pass.
  4. Upon approval, insert user information into the Amazon DynamoDB Accounts table.
  5. Collect home insurance interests and store in an Amazon SQS queue.
  6. Send email notification to the user about the application approval.
  7. Deny the new account application if the checks fail.
  8. Send an email notification to the user about the application denial.

Deploying the application

Before deploying the solution, you need:

To deploy:

  1. From a terminal window, clone the GitHub repo:
    git clone [email protected]:aws-samples/serverless-account-signup-service.git
  2. Change directory:
    cd ./serverless-account-signup-service
  3. Download and install dependencies:
    sam build
  4. Deploy the application to your AWS account:
    sam deploy --guided
  5. During the guided deployment process, enter a valid email address for the parameter “Email” to receive email notifications.
  6. Once deployed, a confirmation email is sent to the provided email address from SNS. Confirm the subscription by clicking the link in the email.
    Email confirmation

To run the application using the AWS CLI, replace the state machine ARN from the output of deployment steps:

aws stepfunctions start-execution \
  --state-machine-arn <StepFunctionArnHere> \
  --input "{\"data\":{\"firstname\":\"Jane\",\"lastname\":\"Doe\",\"identity\":{\"email\":\"[email protected]\",\"ssn\":\"123-45-6789\"},\"address\":{\"street\":\"123 Main St\",\"city\":\"Columbus\",\"state\":\"OH\",\"zip\":\"43219\"},\"interests\":[{\"category\":\"home\",\"type\":\"own\",\"yearBuilt\":2004},{\"category\":\"auto\",\"type\":\"car\",\"yearBuilt\":2012},{\"category\":\"boat\",\"type\":\"snowmobile\",\"yearBuilt\":2020},{\"category\":\"auto\",\"type\":\"motorcycle\",\"yearBuilt\":2018},{\"category\":\"auto\",\"type\":\"RV\",\"yearBuilt\":2015},{\"category\":\"home\",\"type\":\"business\",\"yearBuilt\":2009}]}}"

Paths in Step Functions

Here is the sample payload structure :

{
  "data": {
    "firstname": "Jane",
    "lastname": "Doe",
    "identity": {
      "email": "[email protected]",
      "ssn": "123-45-6789"
    },
    "address": {
      "street": "123 Main St",
      "city": "Columbus",
      "state": "OH",
      "zip": "43219"
    },
    "interests": [
      {"category": "home", "type": "own", "yearBuilt": 2004},
      {"category": "auto", "type": "car", "yearBuilt": 2012},
      {"category": "boat", "type": "snowmobile", "yearBuilt": 2020},
      {"category": "auto", "type": "motorcycle", "yearBuilt": 2018},
      {"category": "auto", "type": "RV", "yearBuilt": 2015},
      {"category": "home", "type": "business", "yearBuilt": 2009}
    ]
  }
}

The payload has data about the new user (identity and address information) and the user’s interests in the types of insurance.

The Compute Blog post on using data flow simulator elaborates on how to use Step Functions paths. To summarize how paths work:

  1. InputPath – What input does a task need?
  2. Parameters – How does the task need the structure of the input to be?
  3. ResultSelectors – What to choose from the task’s output?
  4. ResultPath – Where to put the chosen output?
  5. OutputPath – What output to send to the next state?

The key idea is that the input of downstream states input depends on the output of previous states. JSONPath expressions help structuring input and output between states.

Using JSONPath inside paths

This is how paths are used in the sample application for each type.

InputPath

The first two main tasks in the Step Functions state machine validate the identity and the address of the user. Since both validations are unrelated, they can work independently by using parallel state.

Each state needs the identity and address information provided by the input payload. There is no requirement to provide interests to those states, so InputPath can help answer “What input does a task need?”.

Inside the Check Identity state:

"InputPath": "$.data.identity"

Inside the Check Address state:

"InputPath": "$.data.address"

Parameters

What should the input of the underlying task look like? Check Identity and Check Address use their respective AWS Lambda functions. When Lambda functions or any other AWS service integration is used as a task, the state machine should follow the request syntax of the corresponding service.

For a Lambda function as a task, the state should provide the FunctionName and an optional Payload as parameters. For the Check Identity state, the parameters section looks like:

"Parameters": {
    "FunctionName": "${CheckIdentityFunctionArn}",
    "Payload.$": "$"
}

Here, Payload is the entire identity JSON object provided by InputPath.

ResultSelector

Once the Check Identity task is invoked, the Lambda function successfully validates the user’s identity and responds with an approval response:

{
  "ExecutedVersion": "$LATEST",
  "Payload": {
    "statusCode": "200",
    "body": "{\"approved\": true,\"message\": \"identity validation passed\"}"
  },
  "SdkHttpMetadata": {
    "HttpHeaders": {
      "Connection": "keep-alive",
      "Content-Length": "43",
      "Content-Type": "application/json",
      "Date": "Thu, 16 Apr 2020 17:58:15 GMT",
      "X-Amz-Executed-Version": "$LATEST",
      "x-amzn-Remapped-Content-Length": "0",
      "x-amzn-RequestId": "88fba57b-adbe-467f-abf4-daca36fc9028",
      "X-Amzn-Trace-Id": "root=1-5e989cb6-90039fd8971196666b022b62;sampled=0"
    },
    "HttpStatusCode": 200
  },
  "SdkResponseMetadata": {
    "RequestId": "88fba57b-adbe-467f-abf4-daca36fc9028"
  },
  "StatusCode": 200
}

The identity validation approval must be provided to the downstream states for additional processing. However, the downstream states only need the Payload.body from the preceding JSON.

You can use a combination of intrinsic function and ResultSelector to choose attributes from the task’s output:

"ResultSelector": {
  "identity.$": "States.StringToJson($.Payload.body)"
}

ResultSelector takes the JSON string $.Payload.body and applies States.StringToJson to convert the string to JSON store in a new attribute named identity:

"identity": {
    "approved": true,
    "message": "identity validation passed"
}

When Check Identity and Check Address states finish their work and exit, the step output from each state is captured as a JSON array. This JSON array is the step output of the parallel state. Reconcile the results from the JSON array using the ResultSelector that is available in parallel state.

"ResultSelector": {
    "identityResult.$": "$[0].result.identity",
    "addressResult.$": "$[1].result.address"
}

ResultPath

After ResultSelector, where should the identity result go to in the initial payload? The downstream states need access to the actual input payload in addition to the results from the previous state. ResultPath provides the mechanism to extend the initial payload to add results from the previous state.

ResultPath: "$.result" informs the state machine that any result selected from the task output (actual output if none specified) should go under result JSON attribute and result should get added to the incoming payload. The output from ResultPath looks like:

{
  "data": {
    "firstname": "Jane",
    "lastname": "Doe",
    "identity": {
      "email": "[email protected]",
      "ssn": "123-45-6789"
    },
    "address": {
      "street": "123 Main St",
      "city": "Columbus",
      "state": "OH",
      "zip": "43219"
    },
    "interests": [
      {"category":"home", "type":"own", "yearBuilt":2004},
      {"category":"auto", "type":"car", "yearBuilt":2012},
      {"category":"boat", "type":"snowmobile","yearBuilt":2020},
      {"category":"auto", "type":"motorcycle","yearBuilt":2018},
      {"category":"auto", "type":"RV", "yearBuilt":2015},
      {"category":"home", "type":"business", "yearBuilt":2009}
    ]
  },
  "result": {
    "identity": {
      "approved": true,
      "message": "identity validation passed"
    }
  }
}

The preceding JSON has results from an operation but also the incoming payload is intact for business logic in downstream states.

This pattern ensures that the previous state keeps the payload hydrated for the next state. Use these combinations of paths across all states to make sure that each state has all the information needed.

As with the parallel state’s ResultSelector, an appropriate ResultPath is needed to hold both the results from Check Identity and Check Address to get the below results JSON object added to the payload:

"results": {
  "addressResult": {
    "approved": true,
    "message": "address validation passed"
  },
  "identityResult": {
    "approved": true,
    "message": "identity validation passed"
  }
}

With this approach for all of the downstream states, the input payload is still intact and the state machine has collected results from each state in results.

OutputPath

To return results from the state machine, ideally you do not send back the input payload to the caller of the Step Functions workflow. You can use OutputPath to select a portion of the state output as an end result. OutputPath determines what output to send to the next state.

In the sample application, the last states (Approved Message and Deny Message) defined OutputPath as:

“OutputPath”: “$.results”

The output from the state machine is:

{
  "addressResult": {
    "approved": true,
    "message": "address validation passed"
  },
  "identityResult": {
    "approved": true,
    "message": "identity validation passed"
  },
  "accountAddition": {
    "statusCode": 200
  },
  "homeInsuranceInterests": {
    "statusCode": 200
  },
  "sendApprovedNotification": {
    "statusCode": 200
  }
}

This response strategy is also effective when using a Synchronous Express Workflow for this business logic.

Advanced JSONPath

You can declaratively use advanced JSONPath expressions to apply logic without writing imperative code in utility functions.

Let’s focus on the interests that the new customer has asked for in the input payload. The Step Functions state machine has a state that focuses on interests in the “home” insurance category. Once the new account application is approved and added to the database successfully, the application captures home insurance interests. It adds home-related detail in an HomeInterestsQueue SQS queue and transitions to the Approved Message state.

The interests JSON array has the information about insurance interests. An effective way to get home-related details is to filter out the interests array based on the category “home”. You can try this in data flow simulator:

Data flow simulator

You can apply additional filter expressions to filter data according to your use case. To learn more, visit the the data flow simulator blog.

Inside the state machine JSON, the Home Insurance Interests task has:

"InputPath": "$..interests[?(@.category==home)]"

It uses advanced JSONPath with $.. notation and [?(@.category==home)] filters.

Using advanced expressions on JSONPath is not limited to home insurance interests and can be extended to other categories and business logic.

Cleanup

To delete the sample application, use the latest version of the AWS SAM CLI and run:

sam delete

Conclusion

This post uses a sample application to highlight effective use of JSONPath and data filtering strategies that can be used in Step Functions.

JSONPath provides the flexibility to work on JSON objects and arrays inside the Step Functions states machine by reducing the amount of utility code. It allows developers to build state machines by separating concerns for states’ input and output data. Advanced JSONPath expressions help writing declarative filtering logic without needing imperative utility code, optimizing cost, and performance.

For more serverless learning resources, visit Serverless Land.