Tag Archives: serverless

ICYMI: Serverless Q3 2021

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/icymi-serverless-q3-2021/

Welcome to the 15th edition of the AWS Serverless ICYMI (in case you missed it) quarterly recap. Every quarter, we share all of the most recent product launches, feature enhancements, blog posts, webinars, Twitch live streams, and other interesting things that you might have missed!
Q3 calendar

In case you missed our last ICYMI, check out what happened last quarter here.

AWS Lambda

You can now choose next-generation AWS Graviton2 processors in your Lambda functions. This Arm-based processor architecture can provide up to 19% better performance at 20% lower cost. You can configure functions to use Graviton2 in the AWS Management Console, API, CloudFormation, and CDK. We recommend using the AWS Lambda Power Tuning tool to see how your function compare and determine the price improvement you may see.

All Lambda runtimes built on Amazon Linux 2 support Graviton2, with the exception of versions approaching end-of-support. The AWS Free Tier for Lambda includes functions powered by both x86 and Arm-based architectures.

Create Lambda function with new arm64 option

You can also use the Python 3.9 runtime to develop Lambda functions. You can choose this runtime version in the AWS Management Console, AWS CLI, or AWS Serverless Application Model (AWS SAM). Version 3.9 includes a range of new features and performance improvements.

Lambda now supports Amazon MQ for RabbitMQ as an event source. This makes it easier to develop serverless applications that are triggered by messages in a RabbitMQ queue. This integration does not require a consumer application to monitor queues for updates. The connectivity with the Amazon MQ message broker is managed by the Lambda service.

Lambda has added support for up to 10 GB of memory and 6 vCPU cores in AWS GovCloud (US) Regions and in the Middle East (Bahrain), Asia Pacific (Osaka), and Asia Pacific (Hong Kong) Regions.

AWS Step Functions

Step Functions now integrates with the AWS SDK, supporting over 200 AWS services and 9,000 API actions. You can call services directly from the Amazon States Language definition in the resource field of the task state. This allows you to work with services like DynamoDB, AWS Glue Jobs, or Amazon Textract directly from a Step Functions state machine. To learn more, see the SDK integration tutorial.

AWS Amplify

The Amplify Admin UI now supports importing existing Amazon Cognito user pools and identity pools. This allows you to configure multi-platform apps to use the same user pools with different client IDs.

Amplify CLI now enables command hooks, allowing you to run custom scripts in the lifecycle of CLI commands. You can create bash scripts that run before, during, or after CLI commands. Amplify CLI has also added support for storing environment variables and secrets used by Lambda functions.

Amplify Geo is in developer preview and helps developers provide location-aware features to their frontend web and mobile applications. This uses the Amazon Location Service to provide map UI components.

Amazon EventBridge

The EventBridge schema registry now supports discovery of cross-account events. When schema registry is enabled on a bus, it now generates schemes for events originating from another account. This helps organize and find events in multi-account applications.

Amazon DynamoDB

DynamoDB console

The new DynamoDB console experience is now the default for viewing and managing DynamoDB tables. This makes it easier to manage tables from the navigation pane and also provided a new dedicated Items page. There is also contextual guidance and step-by-step assistance to help you perform common tasks more quickly.

API Gateway

API Gateway can now authenticate clients using certificate-based mutual TLS. Previously, this feature only supported AWS Certificate Manager (ACM). Now, customers can use a server certificate issued by a third-party certificate authority or ACM Private CA. Read more about using mutual TLS authentication with API Gateway.

The Serverless Developer Advocacy team built the Amazon API Gateway CORS Configurator to help you configure cross origin resource scripting (CORS) for REST and HTTP APIs. Fill in the information specific to your API and the AWS SAM configuration is generated for you.

Serverless blog posts

July

August

September

Tech Talks & Events

We hold AWS Online Tech Talks covering serverless topics throughout the year. These are listed in the Serverless section of the AWS Online Tech Talks page. We also regularly deliver talks at conferences and events around the world, speak on podcasts, and record videos you can find to learn in bite-sized chunks.

Here are some from Q3:

Videos

Serverless Land

Serverless Office Hours – Tues 10 AM PT

Weekly live virtual office hours. In each session we talk about a specific topic or technology related to serverless and open it up to helping you with your real serverless challenges and issues. Ask us anything you want about serverless technologies and applications.

July

August

September

DynamoDB Office Hours

Are you an Amazon DynamoDB customer with a technical question you need answered? If so, join us for weekly Office Hours on the AWS Twitch channel led by Rick Houlihan, AWS principal technologist and Amazon DynamoDB expert. See upcoming and previous shows

Still looking for more?

The Serverless landing page has more information. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.

You can also follow the Serverless Developer Advocacy team on Twitter to see the latest news, follow conversations, and interact with the team.

Now — AWS Step Functions Supports 200 AWS Services To Enable Easier Workflow Automation

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/now-aws-step-functions-supports-200-aws-services-to-enable-easier-workflow-automation/

Today AWS Step Functions expands the number of supported AWS services from 17 to over 200 and AWS API Actions from 46 to over 9,000 with its new capability AWS SDK Service Integrations.

When developers build distributed architectures, one of the patterns they use is the workflow-based orchestration pattern. This pattern is helpful for workflow automation inside a service to perform distributed transactions. An example of a distributed transaction is all the tasks required to handle an order and keep track of the transaction status at all times.

Step Functions is a low-code visual workflow service used for workflow automation, to orchestrate services, and help you to apply this pattern. Developers use Step Functions with managed services such as Artificial Intelligence services, Amazon Simple Storage Service (Amazon S3), and Amazon DynamoDB.

Introducing Step Functions AWS SDK Service Integrations
Until today, when developers were building workflows that integrate with AWS services, they had to choose from the 46 supported services integrations that Step Functions provided. If the service integration was not available, they had to code the integration in an AWS Lambda function. This is not ideal as it added more complexity and costs to the application.

Now with Step Functions AWS SDK Service Integrations, developers can integrate their state machines directly to AWS service that has AWS SDK support.

You can create state machines that use AWS SDK Service Integrations with Amazon States Language (ASL), AWS Cloud Development Kit (AWS CDK), or visually using AWS Step Function Workflow Studio. To get started, create a new Task state. Then call AWS SDK services directly from the ASL in the resource field of a task state. To do this, use the following syntax.

arn:aws:states:::aws-sdk:serviceName:apiAction.[serviceIntegrationPattern]

Let me show you how to get started with a demo.

Demo
In this demo, you are building an application that, when given a video file stored in S3, transcribes it and translates from English to Spanish.

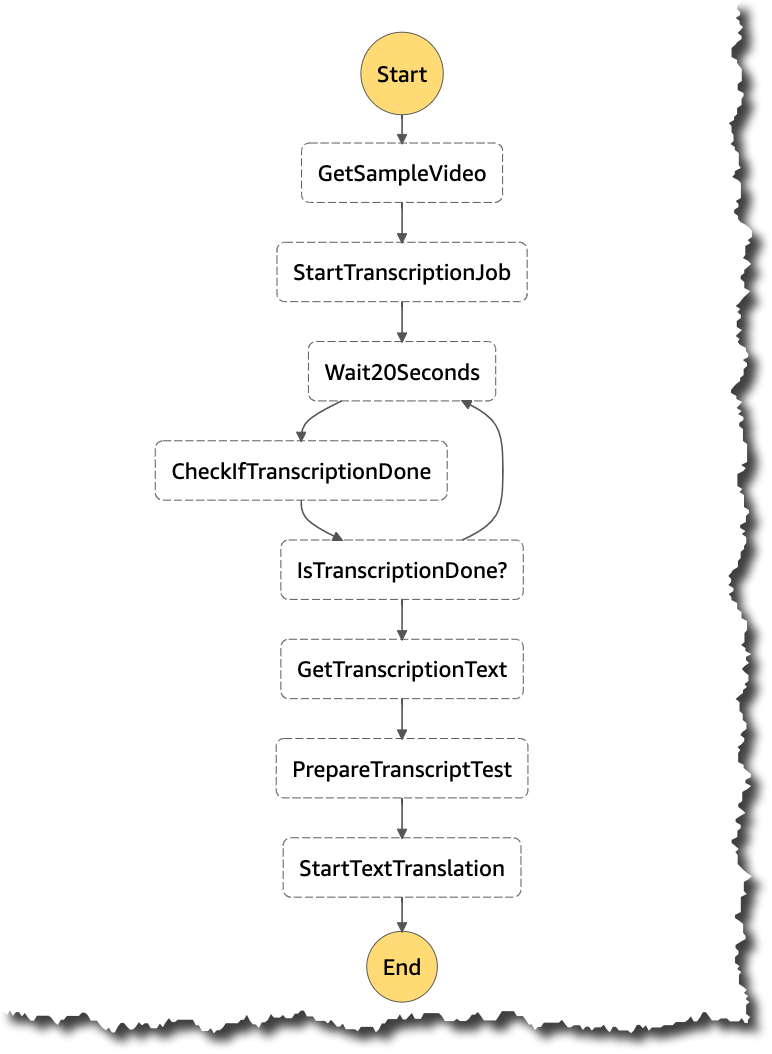
Let’s build this demo with Step Functions. The state machine, with the service integrations, integrates directly to S3, Amazon Transcribe, and Amazon Translate. The API for transcribing is asynchronous. To verify that the transcribing job is completed, you need a polling loop, which waits for it to be ready.

State machine we are going to build

Create the state machine
To follow this demo along, you need to complete these prerequisites:

  • An S3 bucket where you will put the original file that you want to process
  • A video or audio file in English stored in that bucket
  • An S3 bucket where you want the processing to happen

I will show you how to do this demo using the AWS Management Console. If you want to deploy this demo as infrastructure as code, deploy the AWS CloudFormation template for this project.

To get started with this demo, create a new standard state machine. Choose the option Write your workflow in code to build the state machine using ASL. Create a name for the state machine and create a new role.

Creating a state machine

Start a transcription job
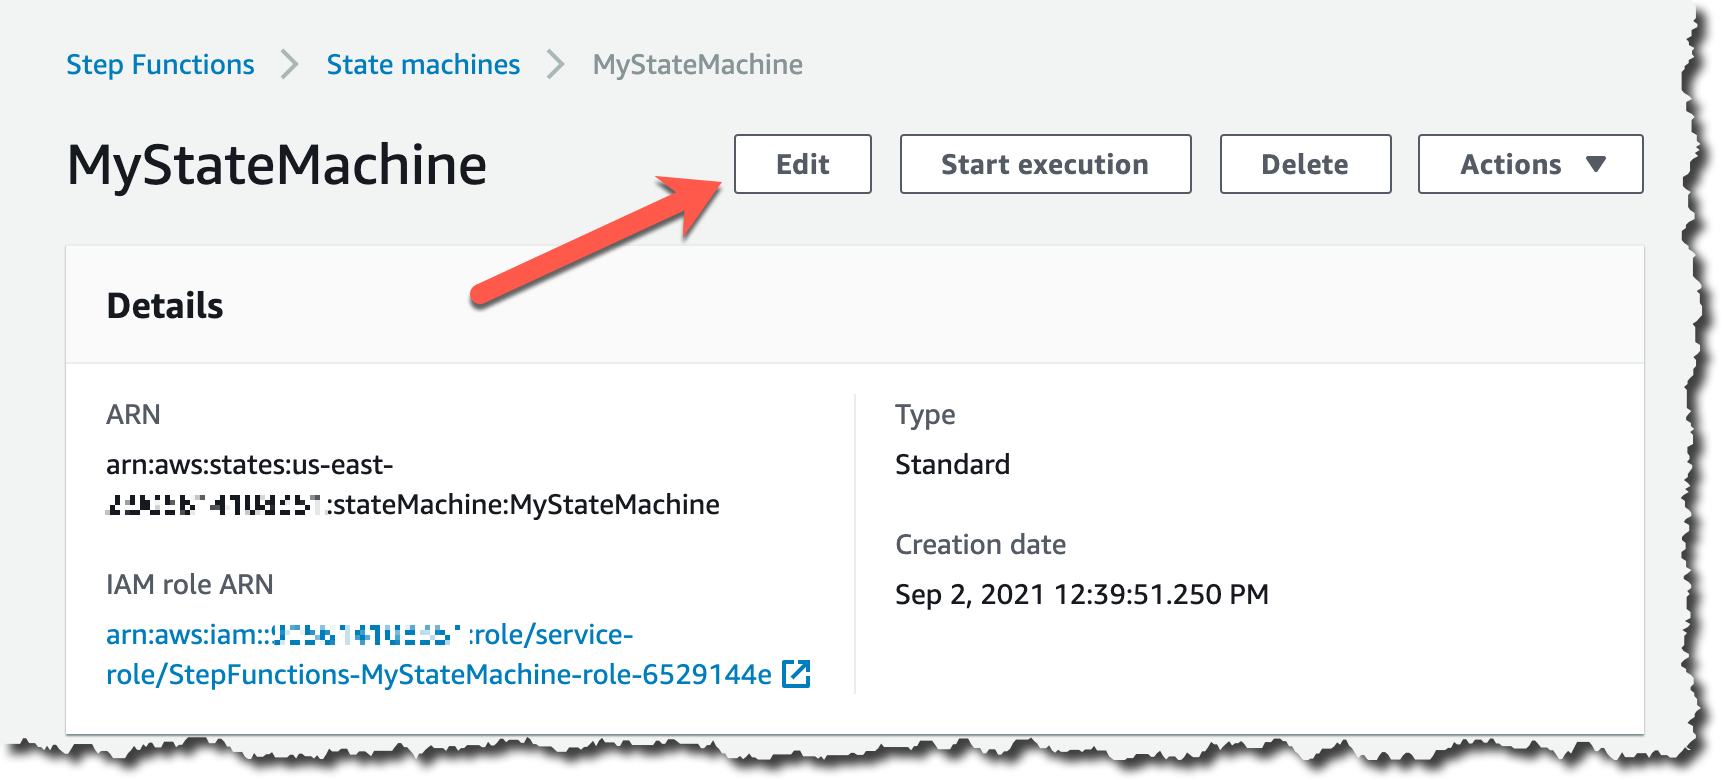
To get started working on the state machine definition, you can Edit the state machine.

Edit the state machine definition

The following piece of ASL code is a state machine with two tasks that are using the new AWS SDK Service Integrations capability. The first task is copying the file from one S3 bucket to another, and the second task is starting the transcription job by directly calling Amazon Transcribe.

For using this new capability from Step Functions, the state type needs to be a Task. You need to specify the service name and API action using this syntax: “arn:aws:states:::aws-sdk:serviceName:apiAction.<serviceIntegrationPattern>”. Use camelCase for apiAction names in the Resource field, such as “copyObject”, and use PascalCase for parameter names in the Parameters field, such as “CopySource”.

For the parameters, find the name and required parameters in the AWS API documentation for this service and API action.

{
  "Comment": "A State Machine that process a video file",
  "StartAt": "GetSampleVideo",
  "States": {
    "GetSampleVideo": {
      "Type": "Task",
      "Resource": "arn:aws:states:::aws-sdk:s3:copyObject",
      "Parameters": {
        "Bucket.$": "$.S3BucketName",
        "Key.$": "$.SampleDataInputKey",
        "CopySource.$": "States.Format('{}/{}',$.SampleDataBucketName,$.SampleDataInputKey)"
      },
      "ResultPath": null,
      "Next": "StartTranscriptionJob"
    },
    "StartTranscriptionJob": {
      "Type": "Task",
      "Resource": "arn:aws:states:::aws-sdk:transcribe:startTranscriptionJob",
      "Parameters": {
        "Media": {
          "MediaFileUri.$": "States.Format('s3://{}/{}',$.S3BucketName,$.SampleDataInputKey)"
        },
        "TranscriptionJobName.$": "$$.Execution.Name",
        "LanguageCode": "en-US",
        "OutputBucketName.$": "$.S3BucketName",
        "OutputKey": "transcribe.json"
      },
      "ResultPath": "$.transcription",
      "End": true
    }
  }
}

In the previous piece of code, you can see an interesting use case of the intrinsic functions that ASL provides. You can construct a string using different parameters. Using intrinsic functions in combination with AWS SDK Service Integrations allows you to manipulate data without the needing a Lambda function. For example, this line:

"MediaFileUri.$": "States.Format('s3://{}/{}',$.S3BucketName,$.SampleDataInputKey)"

Give permissions to the state machine
If you start the execution of the state machine now, it will fail. This state machine doesn’t have permissions to access the S3 buckets or use Amazon Transcribe. Step Functions can’t autogenerate IAM policies for most AWS SDK Service Integrations, so you need to add those to the role manually.

Add those permissions to the IAM role that was created for this state machine. You can find a quick link to the role in the state machine details. Attach the “AmazonTranscribeFullAccess” and the “AmazonS3FullAccess” policies to the role.

Link of the IAM role

Running the state machine for the first time
Now that the permissions are in place, you can run this state machine. This state machine takes as an input the S3 bucket name where the original video is uploaded, the name for the file and the name of the S3 bucket where you want to store this file and do all the processing.

For this to work, this file needs to be a video or audio file and it needs to be in English. When the transcription job is done, it saves the result in the bucket you specify in the input with the name transcribe.json.

 {
  "SampleDataBucketName": "<name of the bucket where the original file is>",
  "SampleDataInputKey": "<name of the original file>",
  "S3BucketName": "<name of the bucket where the processing will happen>"
}

As StartTranscriptionJob is an asynchronous call, you won’t see the results right away. The state machine is only calling the API, and then it completes. You need to wait until the transcription job is ready and then see the results in the output bucket in the file transcribe.json.

Adding a polling loop
Because you want to translate the text using your transcriptions results, your state machine needs to wait for the transcription job to complete. For building an API poller in a state machine, you can use a Task, Wait, and Choice state.

  • Task state gets the job status. In your case, it is calling the service Amazon Transcribe and the API getTranscriptionJob.
  • Wait state waits for 20 seconds, as the transcription job’s length depends on the size of the input file.
  • Choice state moves to the right step based on the result of the job status. If the job is completed, it moves to the next step in the machine, and if not, it keeps on waiting.

States of a polling loop

Wait state
The first of the states you are going to add is the Wait state. This is a simple state that waits for 20 seconds.

"Wait20Seconds": {
        "Type": "Wait",
        "Seconds": 20,
        "Next": "CheckIfTranscriptionDone"
      },

Task state
The next state to add is the Task state, which calls the API getTranscriptionJob. For calling this API, you need to pass the transcription job name. This state returns the job status that is the input of the Choice state.

"CheckIfTranscriptionDone": {
        "Type": "Task",
        "Resource": "arn:aws:states:::aws-sdk:transcribe:getTranscriptionJob",
        "Parameters": {
          "TranscriptionJobName.$": "$.transcription.TranscriptionJob.TranscriptionJobName"
        },
        "ResultPath": "$.transcription",
        "Next": "IsTranscriptionDone?"
      },

Choice state
The Choice state has one rule that checks if the transcription job status is completed. If that rule is true, then it goes to the next state. If not, it goes to the Wait state.

 "IsTranscriptionDone?": {
        "Type": "Choice",
        "Choices": [
          {
            "Variable": "$.transcription.TranscriptionJob.TranscriptionJobStatus",
            "StringEquals": "COMPLETED",
            "Next": "GetTranscriptionText"
          }
        ],
        "Default": "Wait20Seconds"
      },

Getting the transcription text
In this step you are extracting only the transcription text from the output file returned by the transcription job. You need only the transcribed text, as the result file has a lot of metadata that makes the file too long and confusing to translate.

This is a step that you would generally do with a Lambda function. But you can do it directly from the state machine using ASL.

First you need to create a state using AWS SDK Service Integration that gets the result file from S3. Then use another ASL intrinsic function to convert the file text from a String to JSON.

In the next state you can process the file as a JSON object. This state is a Pass state, which cleans the output from the previous state to get only the transcribed text.

 "GetTranscriptionText": {
        "Type": "Task",
        "Resource": "arn:aws:states:::aws-sdk:s3:getObject",
        "Parameters": {
          "Bucket.$": "$.S3BucketName",
          "Key": "transcribe.json"
        },
        "ResultSelector": {
          "filecontent.$": "States.StringToJson($.Body)"
        },
        "ResultPath": "$.transcription",
        "Next": "PrepareTranscriptTest"
      },
  
      "PrepareTranscriptTest" : {
        "Type": "Pass",
        "Parameters": {
          "transcript.$": "$.transcription.filecontent.results.transcripts[0].transcript"
        },
        "Next": "TranslateText"
      },

Translating the text
After preparing the transcribed text, you can translate it. For that you will use Amazon Translate API translateText directly from the state machine. This will be the last state for the state machine and it will return the translated text in the output of this state.

"TranslateText": {
        "Type": "Task",
        "Resource": "arn:aws:states:::aws-sdk:translate:translateText",
        "Parameters": {
          "SourceLanguageCode": "en",
          "TargetLanguageCode": "es",
          "Text.$": "$.transcript"
         },
         "ResultPath": "$.translate",
        "End": true
      }

Add the permissions to the state machine to call the Translate API, by attaching the managed policy “TranslateReadOnly”.

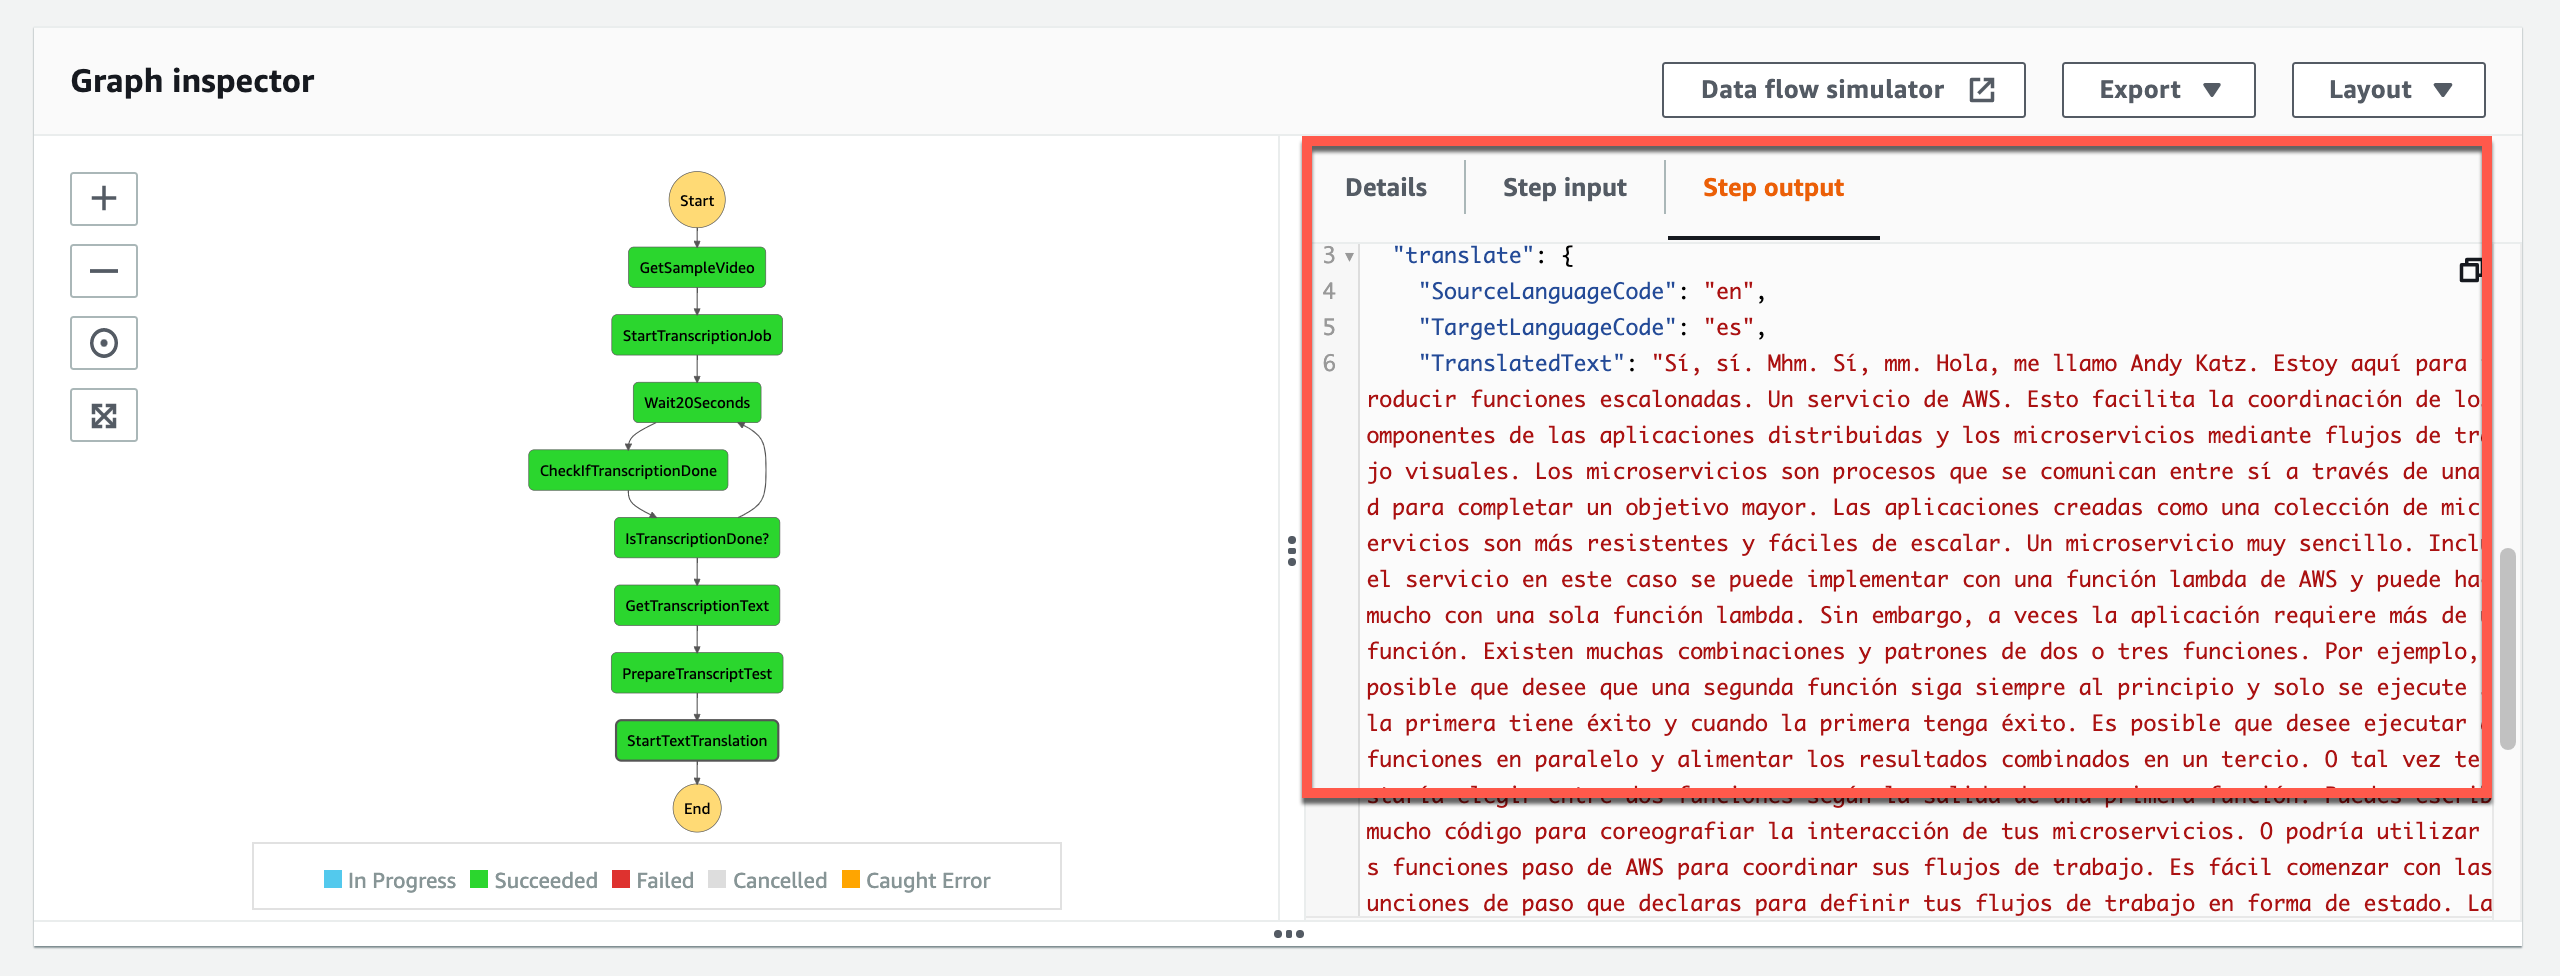
Now with all these in place, you can run your state machine. When the state machine finishes running, you will see the translated text in the output of the last state.

Final state machine

Important things to know
Here are some things that will help you to use AWS SDK Service Integration:

  • Call AWS SDK services directly from the ASL in the resource field of a task state. To do this, use the following syntax: arn:aws:states:::aws-sdk:serviceName:apiAction.[serviceIntegrationPattern]
  • Use camelCase for apiAction names in the Resource field, such as “copyObject”, and use PascalCase for parameter names in the Parameters field, such as “CopySource”.
  • Step Functions can’t autogenerate IAM policies for most AWS SDK Service Integrations, so you need to add those to the IAM role of the state machine manually.
  • Take advantage of ASL intrinsic functions, as those allow you to manipulate the data and avoid using Lambda functions for simple transformations.

Get started today!
AWS SDK Service Integration is generally available in the following regions: US East (N. Virginia), US East (Ohio), US West (Oregon), Canada (Central), Europe (Ireland), Europe (Milan), Africa (Cape Town) and Asia Pacific (Tokyo). It will be generally available in all other commercial regions where Step Functions is available in the coming days.

Learn more about this new capability by reading its documentation.

Marcia

Serverless Live Streaming with Cloudflare Stream

Post Syndicated from Zaid Farooqui original https://blog.cloudflare.com/stream-live/

Serverless Live Streaming with Cloudflare Stream

Serverless Live Streaming with Cloudflare Stream

We’re excited to introduce the open beta of Stream Live, an end-to-end scalable live-streaming platform that allows you to focus on growing your live video apps, not your codebase.

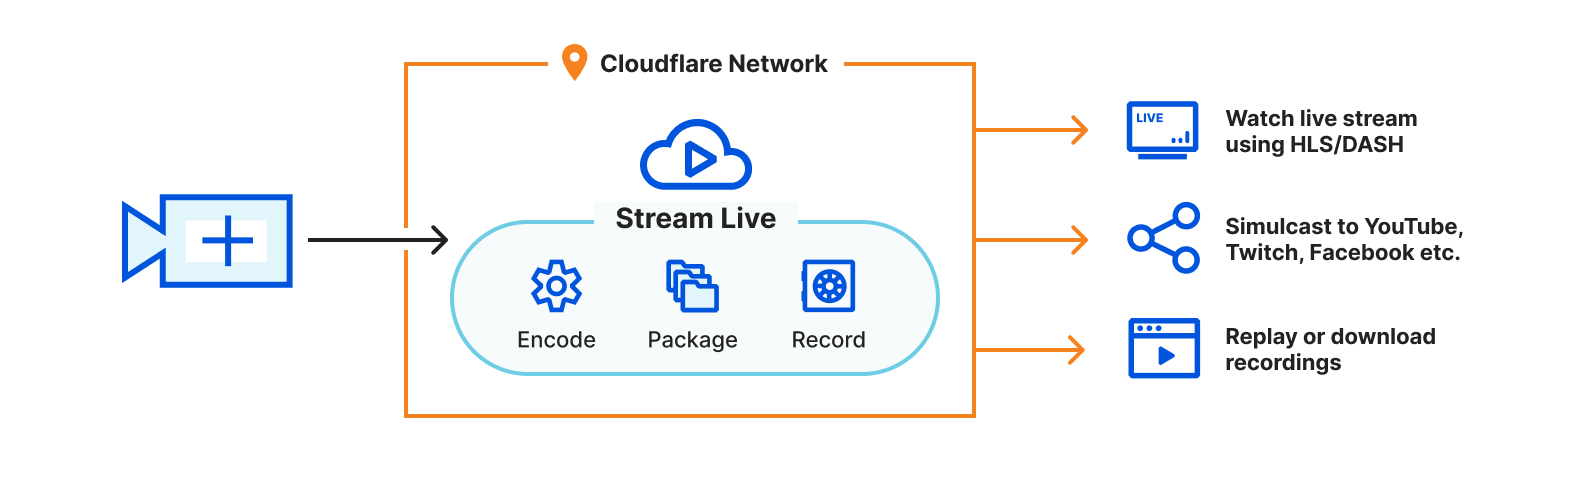
With Stream Live, you can painlessly grow your streaming app to scale to millions of concurrent broadcasters and millions of concurrent users. Start sending live video from mobile or desktop using the industry standard RTMPS protocol to millions of viewers instantly. Stream Live works with the most popular live video broadcasting software you already use, including ffmpeg, OBS or Zoom. Your broadcasts are automatically recorded, optimized and delivered using the Stream player.

When you are building your live infrastructure from scratch, you have to answer a few critical questions:

  1. Which codec(s) are we going to use to encode the videos?”
  2. “Which protocols are we going to use to ingest and deliver videos?”
  3. “How are the different components going to impact latency?”

We built Stream Live, so you don’t have to think about these questions and spend considerable engineering effort answering them. Stream Live abstracts these pesky yet important implementation details by automatically choosing the most compatible codec and streaming protocol for the client device. There is no limit to the number of live broadcasts you can start and viewers you can have on Stream Live. Whether you want to make the next viral video sharing app or securely broadcast all-hands meetings to your company, Stream will scale with you without having to spend months building and maintaining video infrastructure.

Built-in Player and Access Control

Every live video gets an embed code that can be placed inside your app, enabling your users to watch the live stream. You can also use your own player with included support for the two major HTTP streaming formats — HLS and DASH — for a granular control over the user experience.

You can limit who can view your live videos with self-expiring tokenized links for each viewer. When generating the tokenized links, you can define constraints including time-based expiration, geo-fencing and IP restrictions. When building an online learning site or a video sharing app, you can put videos behind authentication, so only logged-in users can view your videos. Or if you are building a live concert platform, you may have agreements to only allow viewers from specific countries or regions. Stream’s signed tokens help you comply with complex and custom rulesets.

Instant Recordings

With Stream Live, you don’t have to wait for a recording to be available after the live broadcast ends. Live videos automatically get converted to recordings in less than a second. Viewers get access to the recording instantly, allowing them to catch up on what they missed.

Instant Scale

Whether your platform has one active broadcaster or ten thousand, Stream Live scales with your use case. You don’t have to worry about adding new compute instances, setting up availability zones or negotiating additional software licenses.

Legacy live video pipelines built in-house typically ingest and encode the live stream continents away in a single location. Video that is ingested far away makes video streaming unreliable, especially for global audiences. All Cloudflare locations run the necessary software to ingest live video in and deliver video out. Once your video broadcast is in the Cloudflare network, Stream Live uses the Cloudflare backbone and Argo to transmit your live video with increased reliability.

Serverless Live Streaming with Cloudflare Stream

Broadcast with 15 second latency

Depending on your video encoder settings, the time between you broadcasting and the video displaying on your viewer’s screens can be as low as fifteen seconds with Stream Live. Low latency allows you to build interactive features such as chat and Q&A into your application. This latency is good for broadcasting meetings, sports, concerts, and worship, but we know it doesn’t cover all uses for live video.

We’re on a mission to reduce the latency Stream Live adds to near-zero. The Cloudflare network is now within 50ms for 95% of the world’s population. We believe we can significantly reduce the delay from the broadcaster to the viewer in the coming months. Finally, in the world of live-streaming, latency is only meaningful once you can assume reliability. By using the Cloudflare network spanning over 250 locations, you get unparalleled reliability that is critical for live events.

Simple and predictable pricing

Stream Live is available as a pay-as-you-go service based on the duration of videos recorded and duration of video viewed.

  • It costs $5 per 1,000 minutes of video storage capacity per month. Live-streamed videos are automatically recorded. There is no additional cost for ingesting the live stream.
  • It costs $1 per 1,000 minutes of video viewed.
  • There are no surprises. You never have to pay hidden costs for video ingest, compute (encoding), egress or storage found in legacy video pipelines.
  • You can control how much you spend with Stream using billing alerts and restrict viewing by creating signed tokens that only work for authorized viewers.

Cloudflare Stream encodes the live stream in multiple quality levels at no additional cost. This ensures smooth playback for your viewers with varying Internet speed. As your viewers move from Wi-Fi to mobile networks, videos continue playing without interruption. Other platforms that offer live-streaming infrastructure tend to add extra fees for adding quality levels that caters to a global audience.

If your use case consists of thousands of concurrent broadcasters or millions of concurrent viewers, reach out to us for volume pricing.

Go live with Stream

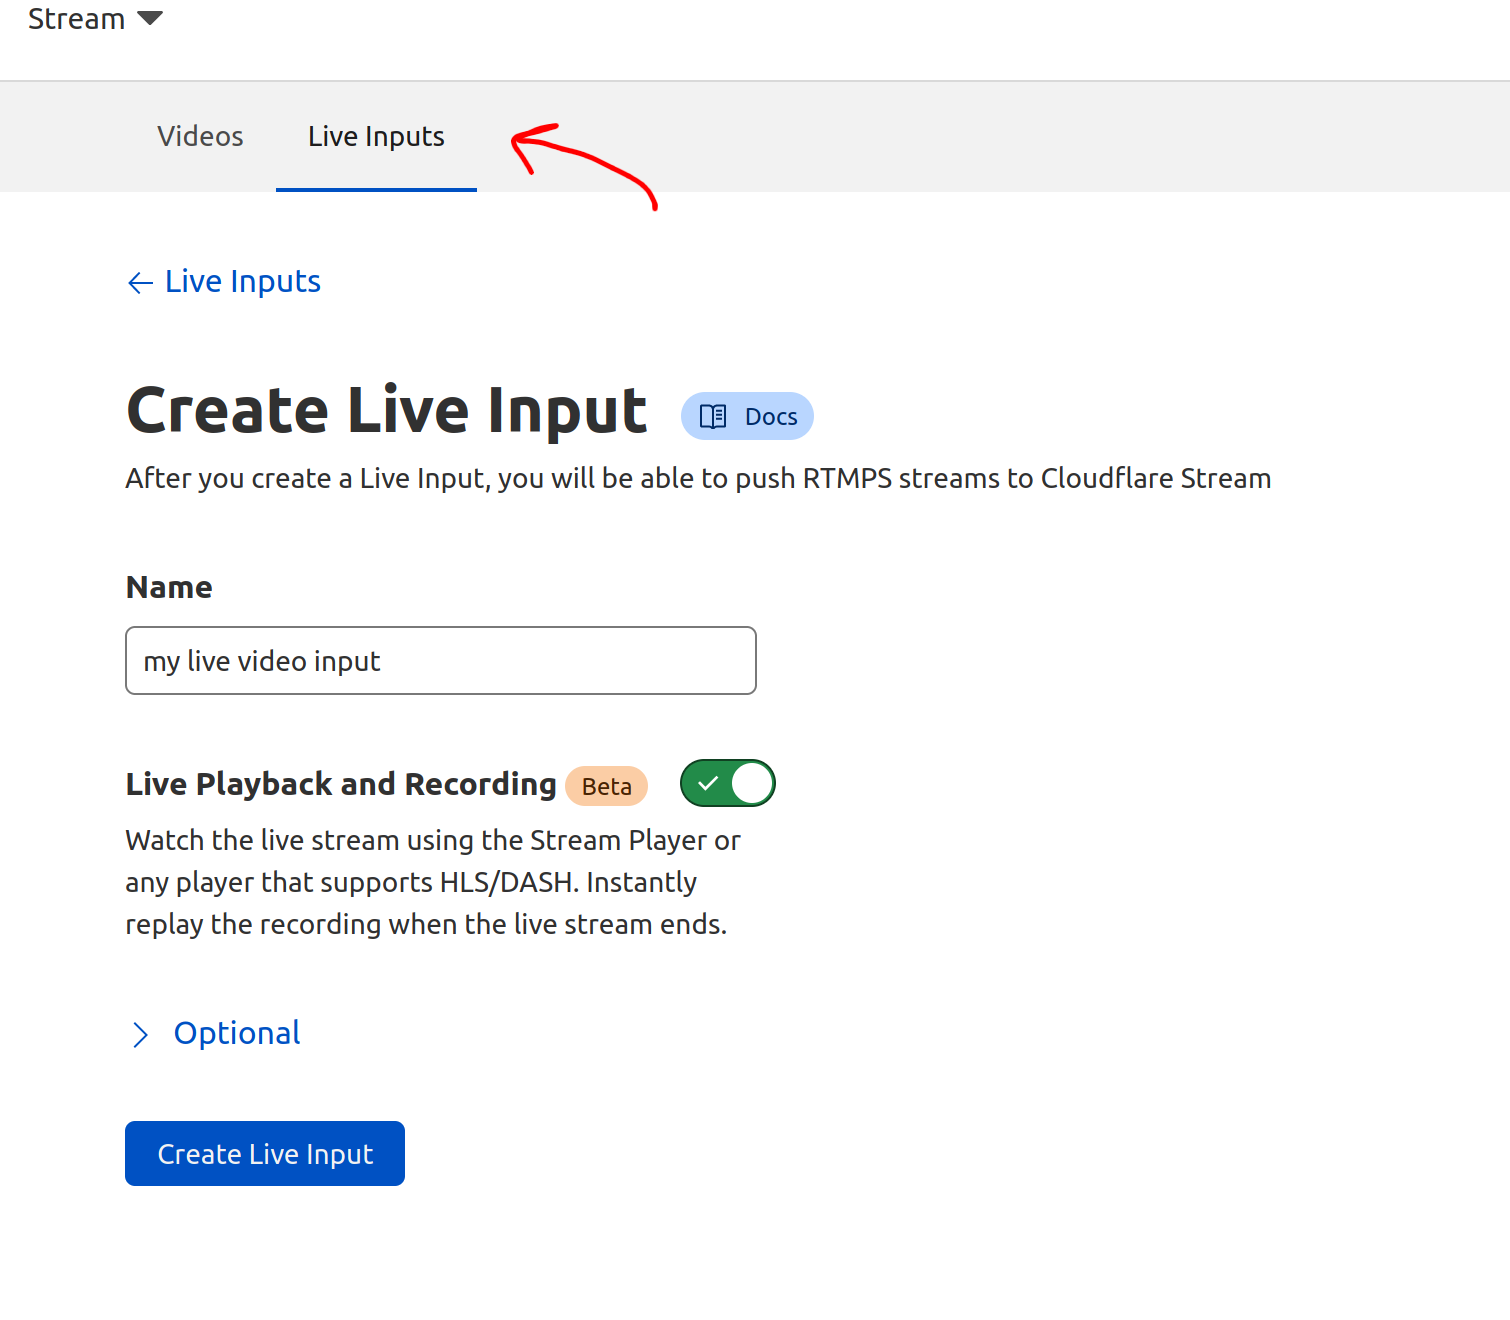
Stream works independent of any domain on Cloudflare. If you already have a Cloudflare account with a Stream subscription, you can begin using Stream Live by clicking on the “Live Input” tab on the Stream Dashboard and creating a new input:

Serverless Live Streaming with Cloudflare Stream

If you are new to Cloudflare, sign up for Cloudflare Stream.

AWS Lambda Functions Powered by AWS Graviton2 Processor – Run Your Functions on Arm and Get Up to 34% Better Price Performance

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-lambda-functions-powered-by-aws-graviton2-processor-run-your-functions-on-arm-and-get-up-to-34-better-price-performance/

Many of our customers (such as Formula One, Honeycomb, Intuit, SmugMug, and Snap Inc.) use the Arm-based AWS Graviton2 processor for their workloads and enjoy better price performance. Starting today, you can get the same benefits for your AWS Lambda functions. You can now configure new and existing functions to run on x86 or Arm/Graviton2 processors.

With this choice, you can save money in two ways. First, your functions run more efficiently due to the Graviton2 architecture. Second, you pay less for the time that they run. In fact, Lambda functions powered by Graviton2 are designed to deliver up to 19 percent better performance at 20 percent lower cost.

With Lambda, you are charged based on the number of requests for your functions and the duration (the time it takes for your code to execute) with millisecond granularity. For functions using the Arm/Graviton2 architecture, duration charges are 20 percent lower than the current pricing for x86. The same 20 percent reduction also applies to duration charges for functions using Provisioned Concurrency.

In addition to the price reduction, functions using the Arm architecture benefit from the performance and security built into the Graviton2 processor. Workloads using multithreading and multiprocessing, or performing many I/O operations, can experience lower execution time and, as a consequence, even lower costs. This is particularly useful now that you can use Lambda functions with up to 10 GB of memory and 6 vCPUs. For example, you can get better performance for web and mobile backends, microservices, and data processing systems.

If your functions don’t use architecture-specific binaries, including in their dependencies, you can switch from one architecture to the other. This is often the case for many functions using interpreted languages such as Node.js and Python or functions compiled to Java bytecode.

All Lambda runtimes built on top of Amazon Linux 2, including the custom runtime, are supported on Arm, with the exception of Node.js 10 that has reached end of support. If you have binaries in your function packages, you need to rebuild the function code for the architecture you want to use. Functions packaged as container images need to be built for the architecture (x86 or Arm) they are going to use.

To measure the difference between architectures, you can create two versions of a function, one for x86 and one for Arm. You can then send traffic to the function via an alias using weights to distribute traffic between the two versions. In Amazon CloudWatch, performance metrics are collected by function versions, and you can look at key indicators (such as duration) using statistics. You can then compare, for example, average and p99 duration between the two architectures.

You can also use function versions and weighted aliases to control the rollout in production. For example, you can deploy the new version to a small amount of invocations (such as 1 percent) and then increase up to 100 percent for a complete deployment. During rollout, you can lower the weight or set it to zero if your metrics show something suspicious (such as an increase in errors).

Let’s see how this new capability works in practice with a few examples.

Changing Architecture for Functions with No Binary Dependencies
When there are no binary dependencies, changing the architecture of a Lambda function is like flipping a switch. For example, some time ago, I built a quiz app with a Lambda function. With this app, you can ask and answer questions using a web API. I use an Amazon API Gateway HTTP API to trigger the function. Here’s the Node.js code including a few sample questions at the beginning:

const questions = [
  {
    question:
      "Are there more synapses (nerve connections) in your brain or stars in our galaxy?",
    answers: [
      "More stars in our galaxy.",
      "More synapses (nerve connections) in your brain.",
      "They are about the same.",
    ],
    correctAnswer: 1,
  },
  {
    question:
      "Did Cleopatra live closer in time to the launch of the iPhone or to the building of the Giza pyramids?",
    answers: [
      "To the launch of the iPhone.",
      "To the building of the Giza pyramids.",
      "Cleopatra lived right in between those events.",
    ],
    correctAnswer: 0,
  },
  {
    question:
      "Did mammoths still roam the earth while the pyramids were being built?",
    answers: [
      "No, they were all exctint long before.",
      "Mammooths exctinction is estimated right about that time.",
      "Yes, some still survived at the time.",
    ],
    correctAnswer: 2,
  },
];

exports.handler = async (event) => {
  console.log(event);

  const method = event.requestContext.http.method;
  const path = event.requestContext.http.path;
  const splitPath = path.replace(/^\/+|\/+$/g, "").split("/");

  console.log(method, path, splitPath);

  var response = {
    statusCode: 200,
    body: "",
  };

  if (splitPath[0] == "questions") {
    if (splitPath.length == 1) {
      console.log(Object.keys(questions));
      response.body = JSON.stringify(Object.keys(questions));
    } else {
      const questionId = splitPath[1];
      const question = questions[questionId];
      if (question === undefined) {
        response = {
          statusCode: 404,
          body: JSON.stringify({ message: "Question not found" }),
        };
      } else {
        if (splitPath.length == 2) {
          const publicQuestion = {
            question: question.question,
            answers: question.answers.slice(),
          };
          response.body = JSON.stringify(publicQuestion);
        } else {
          const answerId = splitPath[2];
          if (answerId == question.correctAnswer) {
            response.body = JSON.stringify({ correct: true });
          } else {
            response.body = JSON.stringify({ correct: false });
          }
        }
      }
    }
  }

  return response;
};

To start my quiz, I ask for the list of question IDs. To do so, I use curl with an HTTP GET on the /questions endpoint:

$ curl https://<api-id>.execute-api.us-east-1.amazonaws.com/questions
[
  "0",
  "1",
  "2"
]

Then, I ask more information on a question by adding the ID to the endpoint:

$ curl https://<api-id>.execute-api.us-east-1.amazonaws.com/questions/1
{
  "question": "Did Cleopatra live closer in time to the launch of the iPhone or to the building of the Giza pyramids?",
  "answers": [
    "To the launch of the iPhone.",
    "To the building of the Giza pyramids.",
    "Cleopatra lived right in between those events."
  ]
}

I plan to use this function in production. I expect many invocations and look for options to optimize my costs. In the Lambda console, I see that this function is using the x86_64 architecture.

Console screenshot.

Because this function is not using any binaries, I switch architecture to arm64 and benefit from the lower pricing.

Console screenshot.

The change in architecture doesn’t change the way the function is invoked or communicates its response back. This means that the integration with the API Gateway, as well as integrations with other applications or tools, are not affected by this change and continue to work as before.

I continue my quiz with no hint that the architecture used to run the code has changed in the backend. I answer back to the previous question by adding the number of the answer (starting from zero) to the question endpoint:

$ curl https://<api-id>.execute-api.us-east-1.amazonaws.com/questions/1/0
{
  "correct": true
}

That’s correct! Cleopatra lived closer in time to the launch of the iPhone than the building of the Giza pyramids. While I am digesting this piece of information, I realize that I completed the migration of the function to Arm and optimized my costs.

Changing Architecture for Functions Packaged Using Container Images
When we introduced the capability to package and deploy Lambda functions using container images, I did a demo with a Node.js function generating a PDF file with the PDFKit module. Let’s see how to migrate this function to Arm.

Each time it is invoked, the function creates a new PDF mail containing random data generated by the faker.js module. The output of the function is using the syntax of the Amazon API Gateway to return the PDF file using Base64 encoding. For convenience, I replicate the code (app.js) of the function here:

const PDFDocument = require('pdfkit');
const faker = require('faker');
const getStream = require('get-stream');

exports.lambdaHandler = async (event) => {

    const doc = new PDFDocument();

    const randomName = faker.name.findName();

    doc.text(randomName, { align: 'right' });
    doc.text(faker.address.streetAddress(), { align: 'right' });
    doc.text(faker.address.secondaryAddress(), { align: 'right' });
    doc.text(faker.address.zipCode() + ' ' + faker.address.city(), { align: 'right' });
    doc.moveDown();
    doc.text('Dear ' + randomName + ',');
    doc.moveDown();
    for(let i = 0; i < 3; i++) {
        doc.text(faker.lorem.paragraph());
        doc.moveDown();
    }
    doc.text(faker.name.findName(), { align: 'right' });
    doc.end();

    pdfBuffer = await getStream.buffer(doc);
    pdfBase64 = pdfBuffer.toString('base64');

    const response = {
        statusCode: 200,
        headers: {
            'Content-Length': Buffer.byteLength(pdfBase64),
            'Content-Type': 'application/pdf',
            'Content-disposition': 'attachment;filename=test.pdf'
        },
        isBase64Encoded: true,
        body: pdfBase64
    };
    return response;
};

To run this code, I need the pdfkit, faker, and get-stream npm modules. These packages and their versions are described in the package.json and package-lock.json files.

I update the FROM line in the Dockerfile to use an AWS base image for Lambda for the Arm architecture. Given the chance, I also update the image to use Node.js 14 (I was using Node.js 12 at the time). This is the only change I need to switch architecture.

FROM public.ecr.aws/lambda/nodejs:14-arm64
COPY app.js package*.json ./
RUN npm install
CMD [ "app.lambdaHandler" ]

For the next steps, I follow the post I mentioned previously. This time I use random-letter-arm for the name of the container image and for the name of the Lambda function. First, I build the image:

$ docker build -t random-letter-arm .

Then, I inspect the image to check that it is using the right architecture:

$ docker inspect random-letter-arm | grep Architecture

"Architecture": "arm64",

To be sure the function works with the new architecture, I run the container locally.

$ docker run -p 9000:8080 random-letter-arm:latest

Because the container image includes the Lambda Runtime Interface Emulator, I can test the function locally:

$ curl -XPOST "http://localhost:9000/2015-03-31/functions/function/invocations" -d '{}'

It works! The response is a JSON document containing a base64-encoded response for the API Gateway:

{
    "statusCode": 200,
    "headers": {
        "Content-Length": 2580,
        "Content-Type": "application/pdf",
        "Content-disposition": "attachment;filename=test.pdf"
    },
    "isBase64Encoded": true,
    "body": "..."
}

Confident that my Lambda function works with the arm64 architecture, I create a new Amazon Elastic Container Registry repository using the AWS Command Line Interface (CLI):

$ aws ecr create-repository --repository-name random-letter-arm --image-scanning-configuration scanOnPush=true

I tag the image and push it to the repo:

$ docker tag random-letter-arm:latest 123412341234.dkr.ecr.us-east-1.amazonaws.com/random-letter-arm:latest
$ aws ecr get-login-password | docker login --username AWS --password-stdin 123412341234.dkr.ecr.us-east-1.amazonaws.com
$ docker push 123412341234.dkr.ecr.us-east-1.amazonaws.com/random-letter-arm:latest

In the Lambda console, I create the random-letter-arm function and select the option to create the function from a container image.

Console screenshot.

I enter the function name, browse my ECR repositories to select the random-letter-arm container image, and choose the arm64 architecture.

Console screenshot.

I complete the creation of the function. Then, I add the API Gateway as a trigger. For simplicity, I leave the authentication of the API open.

Console screenshot.

Now, I click on the API endpoint a few times and download some PDF mails generated with random data:

Screenshot of some PDF files.

The migration of this Lambda function to Arm is complete. The process will differ if you have specific dependencies that do not support the target architecture. The ability to test your container image locally helps you find and fix issues early in the process.

Comparing Different Architectures with Function Versions and Aliases
To have a function that makes some meaningful use of the CPU, I use the following Python code. It computes all prime numbers up to a limit passed as a parameter. I am not using the best possible algorithm here, that would be the sieve of Eratosthenes, but it’s a good compromise for an efficient use of memory. To have more visibility, I add the architecture used by the function to the response of the function.

import json
import math
import platform
import timeit

def primes_up_to(n):
    primes = []
    for i in range(2, n+1):
        is_prime = True
        sqrt_i = math.isqrt(i)
        for p in primes:
            if p > sqrt_i:
                break
            if i % p == 0:
                is_prime = False
                break
        if is_prime:
            primes.append(i)
    return primes

def lambda_handler(event, context):
    start_time = timeit.default_timer()
    N = int(event['queryStringParameters']['max'])
    primes = primes_up_to(N)
    stop_time = timeit.default_timer()
    elapsed_time = stop_time - start_time

    response = {
        'machine': platform.machine(),
        'elapsed': elapsed_time,
        'message': 'There are {} prime numbers <= {}'.format(len(primes), N)
    }
    
    return {
        'statusCode': 200,
        'body': json.dumps(response)
    }

I create two function versions using different architectures.

Console screenshot.

I use a weighted alias with 50% weight on the x86 version and 50% weight on the Arm version to distribute invocations evenly. When invoking the function through this alias, the two versions running on the two different architectures are executed with the same probability.

Console screenshot.

I create an API Gateway trigger for the function alias and then generate some load using a few terminals on my laptop. Each invocation computes prime numbers up to one million. You can see in the output how two different architectures are used to run the function.

$ while True
  do
    curl https://<api-id>.execute-api.us-east-1.amazonaws.com/default/prime-numbers\?max\=1000000
  done

{"machine": "aarch64", "elapsed": 1.2595275060011772, "message": "There are 78498 prime numbers <= 1000000"}
{"machine": "aarch64", "elapsed": 1.2591725109996332, "message": "There are 78498 prime numbers <= 1000000"}
{"machine": "x86_64", "elapsed": 1.7200910530000328, "message": "There are 78498 prime numbers <= 1000000"}
{"machine": "x86_64", "elapsed": 1.6874686619994463, "message": "There are 78498 prime numbers <= 1000000"}
{"machine": "x86_64", "elapsed": 1.6865161940004327, "message": "There are 78498 prime numbers <= 1000000"}
{"machine": "aarch64", "elapsed": 1.2583248640003148, "message": "There are 78498 prime numbers <= 1000000"}
...

During these executions, Lambda sends metrics to CloudWatch and the function version (ExecutedVersion) is stored as one of the dimensions.

To better understand what is happening, I create a CloudWatch dashboard to monitor the p99 duration for the two architectures. In this way, I can compare the performance of the two environments for this function and make an informed decision on which architecture to use in production.

Console screenshot.

For this particular workload, functions are running much faster on the Graviton2 processor, providing a better user experience and much lower costs.

Comparing Different Architectures with Lambda Power Tuning
The AWS Lambda Power Tuning open-source project, created by my friend Alex Casalboni, runs your functions using different settings and suggests a configuration to minimize costs and/or maximize performance. The project has recently been updated to let you compare two results on the same chart. This comes in handy to compare two versions of the same function, one using x86 and the other Arm.

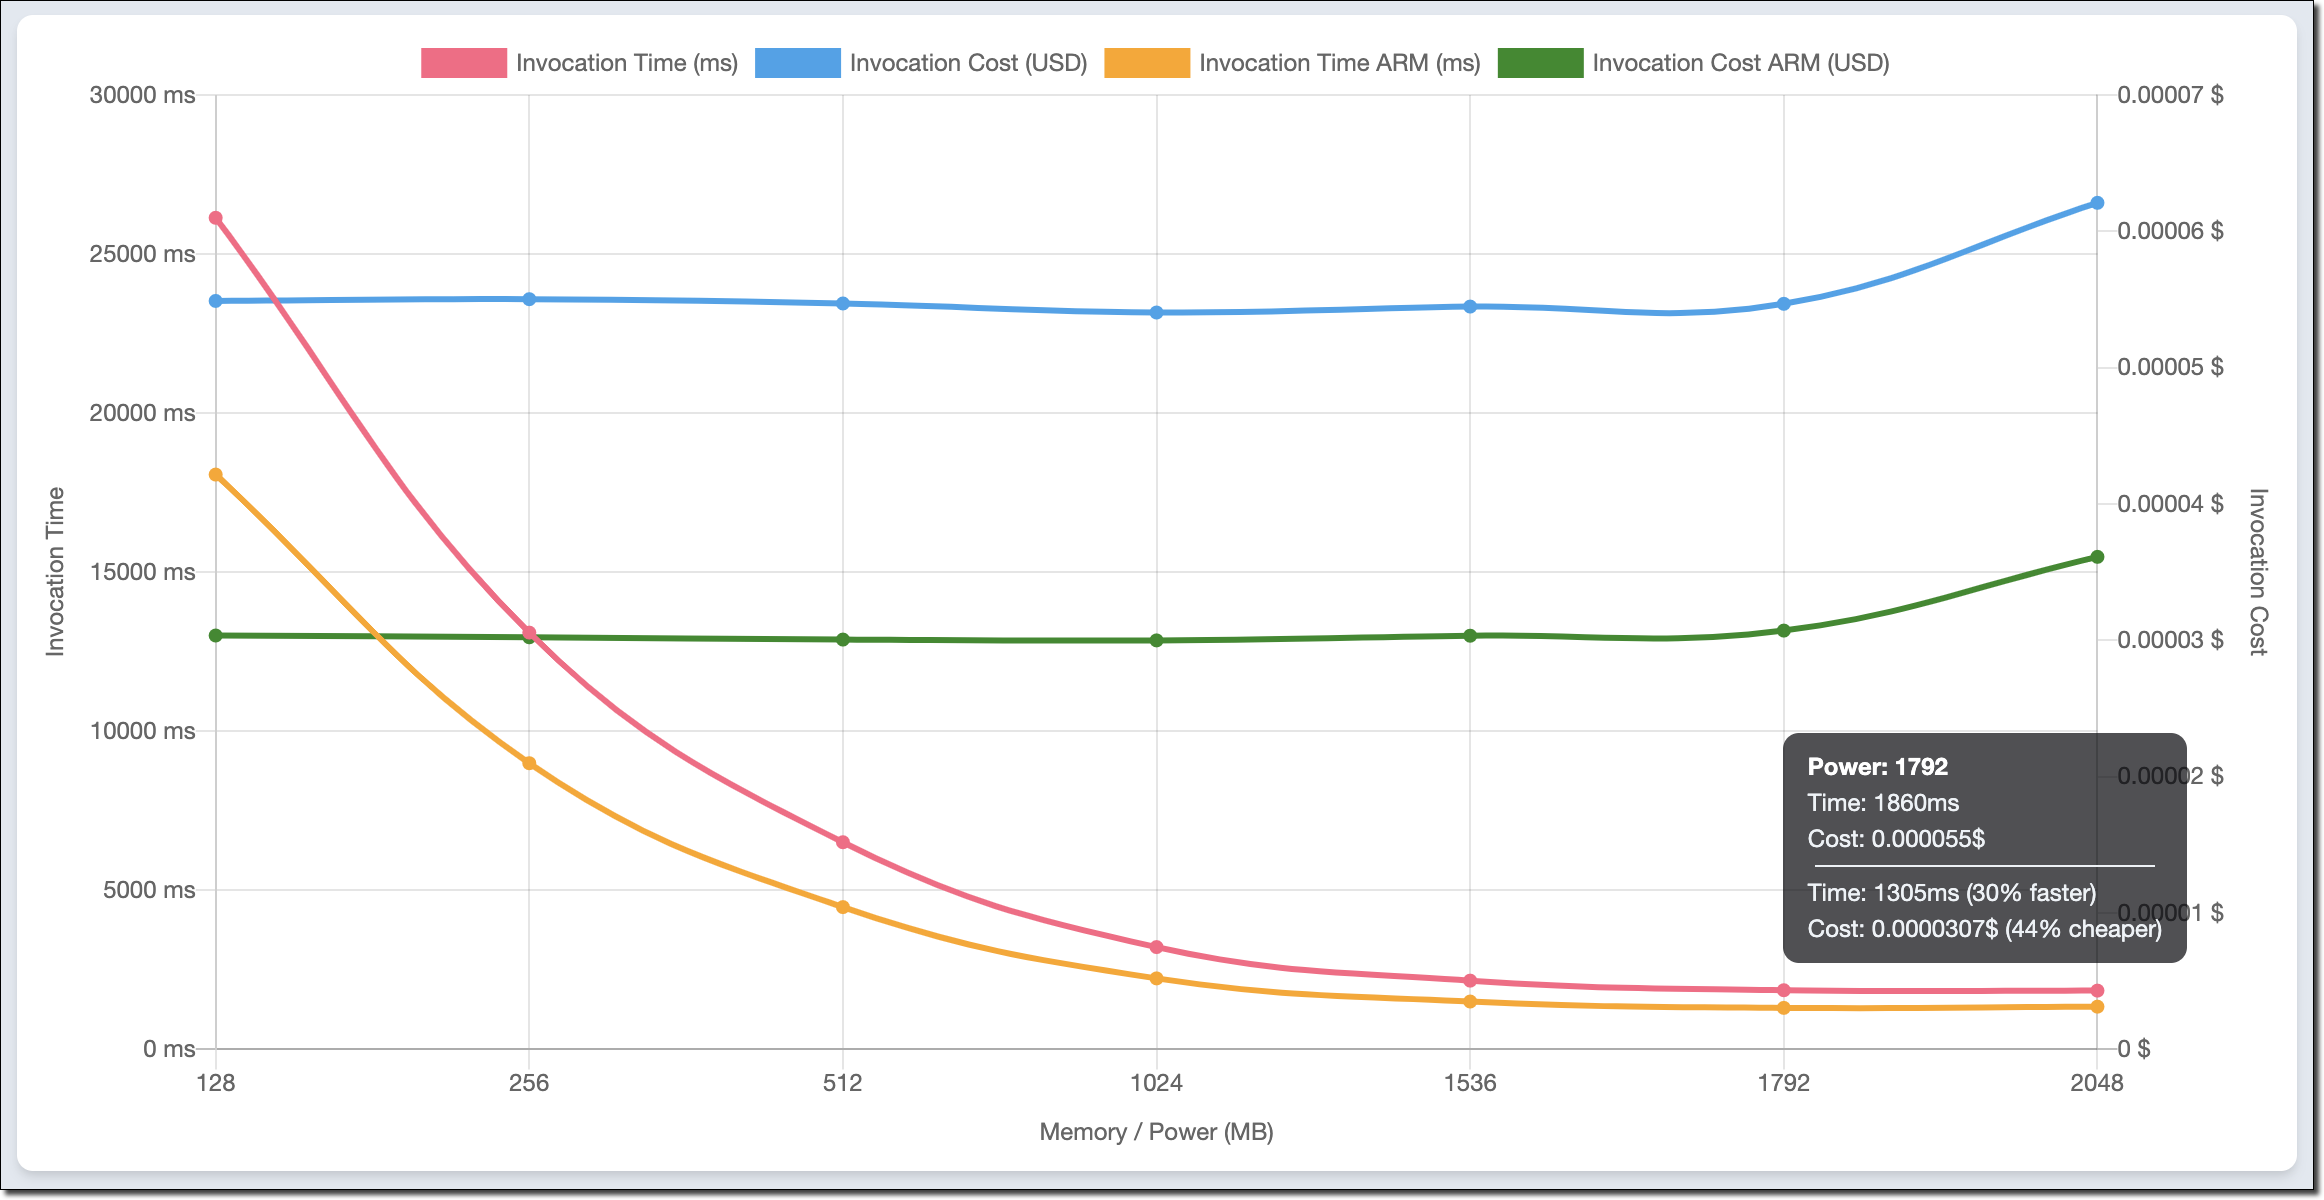
For example, this chart compares x86 and Arm/Graviton2 results for the function computing prime numbers I used earlier in the post:

Chart.

The function is using a single thread. In fact, the lowest duration for both architectures is reported when memory is configured with 1.8 GB. Above that, Lambda functions have access to more than 1 vCPU, but in this case, the function can’t use the additional power. For the same reason, costs are stable with memory up to 1.8 GB. With more memory, costs increase because there are no additional performance benefits for this workload.

I look at the chart and configure the function to use 1.8 GB of memory and the Arm architecture. The Graviton2 processor is clearly providing better performance and lower costs for this compute-intensive function.

Availability and Pricing
You can use Lambda Functions powered by Graviton2 processor today in US East (N. Virginia), US East (Ohio), US West (Oregon), Europe (Frankfurt), Europe (Ireland), EU (London), Asia Pacific (Mumbai), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo).

The following runtimes running on top of Amazon Linux 2 are supported on Arm:

  • Node.js 12 and 14
  • Python 3.8 and 3.9
  • Java 8 (java8.al2) and 11
  • .NET Core 3.1
  • Ruby 2.7
  • Custom Runtime (provided.al2)

You can manage Lambda Functions powered by Graviton2 processor using AWS Serverless Application Model (SAM) and AWS Cloud Development Kit (AWS CDK). Support is also available through many AWS Lambda Partners such as AntStack, Check Point, Cloudwiry, Contino, Coralogix, Datadog, Lumigo, Pulumi, Slalom, Sumo Logic, Thundra, and Xerris.

Lambda functions using the Arm/Graviton2 architecture provide up to 34 percent price performance improvement. The 20 percent reduction in duration costs also applies when using Provisioned Concurrency. You can further reduce your costs by up to 17 percent with Compute Savings Plans. Lambda functions powered by Graviton2 are included in the AWS Free Tier up to the existing limits. For more information, see the AWS Lambda pricing page.

You can find help to optimize your workloads for the AWS Graviton2 processor in the Getting started with AWS Graviton repository.

Start running your Lambda functions on Arm today.

Danilo

Building an API poller with AWS Step Functions and AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/building-an-api-poller-with-aws-step-functions-and-aws-lambda/

This post is written by Siarhei Kazhura, Solutions Architect.

Many customers have to integrate with external APIs. One of the most common use cases is data synchronization between a customer and their trusted partner.

There are multiple ways of doing this. For example, the customer can provide a webhook that the partner can call to notify the customer of any data changes. Often the customer has to poll the partner API to stay up to date with the changes. Even when using a webhook, a complete synchronization happening on schedule is necessary.

Furthermore, the partner API may not allow loading all the data at once. Often, a pagination solution allows loading only a portion of the data via one API call. That requires the customer to build an API poller that can iterate through all the data pages to fully synchronize.

This post demonstrates a sample API poller architecture, using AWS Step Functions for orchestration, AWS Lambda for business logic processing, along with Amazon API Gateway, Amazon DynamoDB, Amazon SQS, Amazon EventBridge, Amazon Simple Storage Service (Amazon S3), and the AWS Serverless Application Model (AWS SAM).

Overall architecture

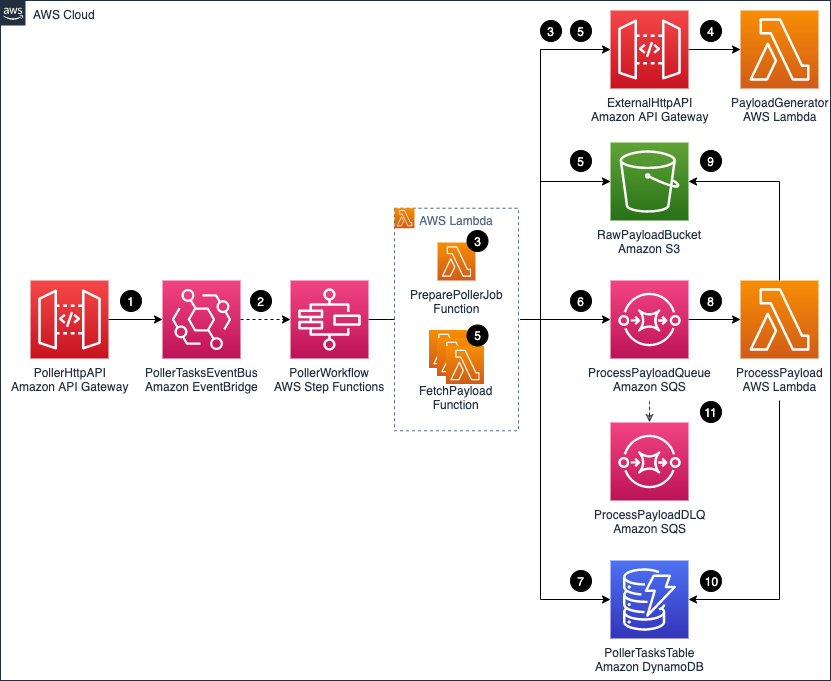
Reference architecture

The application consists of the following resources defined in the AWS SAM template:

  • PollerHttpAPI: The front door of the application represented via an API Gateway HTTP API.
  • PollerTasksEventBus: An EventBridge event bus that is directly integrated with API Gateway. That means that an API call results in an event being created in the event bus. EventBridge allows you to route the event to the destination you want. It also allows you to archive and replay events as needed, adding resiliency to the architecture. Each event has a unique id that this solution uses for tracing purposes.
  • PollerWorkflow: The Step Functions workflow.
  • ExternalHttpApi: The API Gateway HTTP API that is used to simulate an external API.
  • PayloadGenerator: A Lambda function that is generating a sample payload for the application.
  • RawPayloadBucket: An Amazon S3 bucket that stores the payload received from the external API. The Step Functions supported payload size is up to 256 KB. For larger payloads, you can store the API payload in an S3 bucket.
  • PollerTasksTable: A DynamoDB table that tracks each poller’s progress. The table has a TimeToLive (TTL) attribute enabled. This automatically discards tasks that exceed the TTL value.
  • ProcessPayoadQueue: Amazon SQS queue that decouples our payload fetching mechanism from our payload processing mechanism.
  • ProcessPayloadDLQ: Amazon SQS dead letter queue is collecting the messages that we are unable to process.
  • ProcessPayload: Lambda function that is processing the payload. The function reports progress of each poller task, marking it as complete when given payload is processed successfully.

Data flow

Data flow

When the API poller runs:

  1. After a POST call is made to PollerHttpAPI /jobs endpoint, an event containing the API payload is put on the PollerTasksEventBus.
  2. The event triggers the PollerWorkflow execution. The event payload (including the event unique id) is passed to the PollerWorkflow.
  3. The PollerWorkflow starts by running the PreparePollerJob function. The function retrieves required metadata from the ExternalHttpAPI. For example, the total number of records to be loaded and maximum records that can be retrieved via a single API call. The function creates poller tasks that are required to fetch the data. The task calculation is based on the metadata received.
  4. The PayloadGenerator function generates random ExternalHttpAPI payloads. The PayloadGenerator function also includes code that simulates random errors and delays.
  5. All the tasks are processed in a fan-out fashion using dynamic-parallelism. The FetchPayload function retrieves a payload chunk from the ExternalHttpAPI, and the payload is saved to the RawPayloadBucket.
  6. A message, containing a pointer to the payload file stored in the RawPayloadBucket, the id of the task, and other task information is sent to the ProcessPayloadQueue. Each message has jobId and taskId attributes. This helps correlate the message with the poller task.
  7. Anytime a task is changing its status (for example, when the payload is saved to S3 bucket, or when a message has been sent to SQS queue) the progress is reported to the PollerTaskTable.
  8. The ProcessPayload function is long-polling the ProcessPayloadQueue. As messages appear on the queue, they are being processed.
  9. The ProcessPayload function is removing an object from the RawPayloadBucket. This is done to illustrate a type of processing that you can do with the payload stored in the S3 bucket.
  10. After the payload is removed successfully, the progress is reported to the PollerTasksTable. The corresponding task is marked as complete.
  11. If the ProcessPayload function experiences errors, it tries to process the message several times. If it cannot process the message, the message is pushed to the ProcessPayloadDLQ. This is configured as a dead-letter queue for the ProcessPayloadQueue.

Step Functions state machine

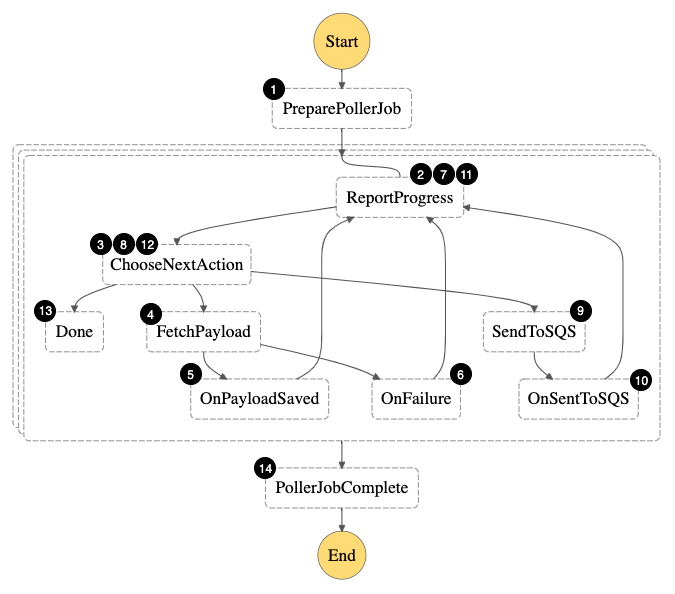
State machine

The Step Functions state machine orchestrates the following workflow:

  1. Fetch external API metadata and create tasks required to fetch all payload.
  2. For each task, report that the task has entered Started state.
  3. Since the task is in the Started state, the next action is FetchPayload
  4. Fetch payload from the external API and store it in an S3 bucket.
  5. In case of success, move the task to a PayloadSaved state.
  6. In case of an error, report that the task is in a failed state.
  7. Report that the task has entered PayloadSaved (or failed) state.
  8. In case the task is in the PayloadSaved state, move to the SendToSQS step. If the task is in a failed state, exit.
  9. Send the S3 object pointer and additional task metadata to the SQS queue.
  10. Move the task to an enqueued state.
  11. Report that the task has entered enqueued state.
  12. Since the task is in the enqueued state, we are done.
  13. Combine the results for a single task execution.
  14. Combine the results for all the task executions.

Prerequisites to implement the solution

The following prerequisites are required for this walk-through:

Step-by-step instructions

You can use AWS Cloud9, or your preferred IDE, to deploy the AWS SAM template. Refer to the cleanup section of this post for instructions to delete the resources to stop incurring any further charges.

  1. Clone the repository by running the following command:
    git clone https://github.com/aws-samples/sam-api-poller.git
  2. Change to the sam-api-poller directory, install dependencies and build the application:
    npm install
    sam build -c -p
  3. Package and deploy the application to the AWS Cloud, following the series of prompts. Name the stack sam-api-poller:
    sam deploy --guided --capabilities CAPABILITY_NAMED_IAM
  4. SAM outputsAfter stack creation, you see ExternalHttpApiUrl, PollerHttpApiUrl, StateMachineName, and RawPayloadBucket in the outputs section.
    CloudFormation outputs
  5. Store API URLs as variables:
    POLLER_HTTP_API_URL=$(aws cloudformation describe-stacks --stack-name sam-api-poller --query "Stacks[0].Outputs[?OutputKey=='PollerHttpApiUrl'].OutputValue" --output text)
    
    EXTERNAL_HTTP_API_URL=$(aws cloudformation describe-stacks --stack-name sam-api-poller --query "Stacks[0].Outputs[?OutputKey=='ExternalHttpApiUrl'].OutputValue" --output text)
  6. Make an API call:
    REQUEST_PYLOAD=$(printf '{"url":"%s/payload"}' $EXTERNAL_HTTP_API_URL)
    EVENT_ID=$(curl -d $REQUEST_PYLOAD -H "Content-Type: application/json" -X POST $POLLER_HTTP_API_URL/jobs | jq -r '.Entries[0].EventId')
    
  7. The EventId that is returned by the API is stored in a variable. You can trace all the poller tasks related to this execution via the EventId. Run the following command to track task progress:
    curl -H "Content-Type: application/json" $POLLER_HTTP_API_URL/jobs/$EVENT_ID
  8. Inspect the output. For example:
    {"Started":9,"PayloadSaved":15,"Enqueued":11,"SuccessfullyCompleted":0,"FailedToComplete":0,"Total":35}%
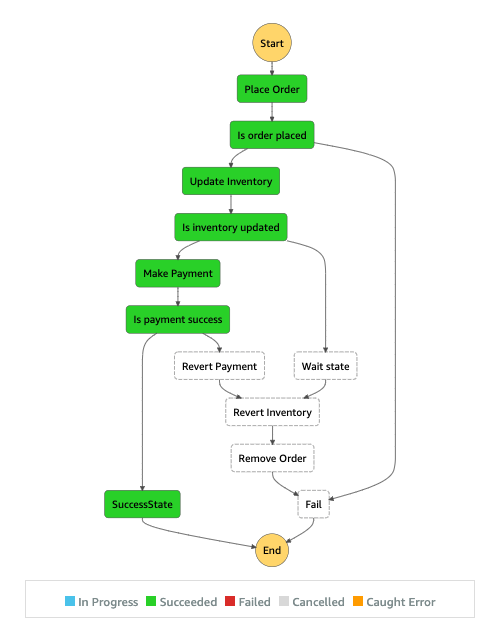
  9. Navigate to the Step Functions console and choose the state machine name that corresponds to the StateMachineName from step 4. Choose an execution and inspect the visual flow.
    Workflow
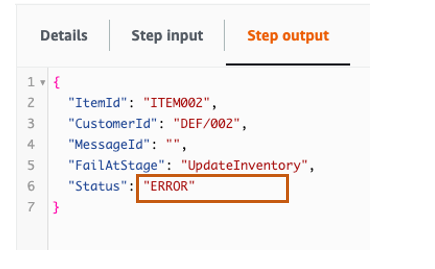
  10. Inspect each individual step by clicking on it. For example, for the PollerJobComplete step, you see:
    Step output

Cleanup

  1. Make sure that the `RawPayloadBucket` bucket is empty. In case the bucket has some files, follow emptying a bucket guide.
  2. To delete all the resources permanently and stop incurring costs, navigate to the CloudFormation console. Select the sam-api-poller stack, then choose Delete -> Delete stack.

Cost optimization

For Step Functions, this example uses the Standard Workflow type because it has a visualization tool. If you are planning to re-use the solution, consider switching from standard to Express Workflows. This may be a better option for the type of workload in this example.

Conclusion

This post shows how to use Step Functions, Lambda, EventBridge, S3, API Gateway HTTP APIs, and SQS to build a serverless API poller. I show how you can deploy a sample solution, process sample payload, and store it to S3.

I also show how to perform clean-up to avoid any additional charges. You can modify this example for your needs and build a custom solution for your use case.

For more serverless learning resources, visit Serverless Land.

Creating a serverless face blurring service for photos in Amazon S3

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/creating-a-serverless-face-blurring-service-for-photos-in-amazon-s3/

Many workloads process photos or imagery from web applications or mobile applications. For privacy reasons, it can be useful to identify and blur faces in these photos. This blog post shows how to build a serverless face blurring service for photos uploaded to an Amazon S3 bucket.

The example application uses the AWS Serverless Application Model (AWS SAM), enabling you to deploy the application more easily in your own AWS account. This walkthrough creates resources covered in the AWS Free Tier but usage beyond the Free Tier allowance may incur cost. To set up the example, visit the GitHub repo and follow the instructions in the README.md file.

Overview

Using a serverless approach, this face blurring microservice runs on demand in response to new photos being uploaded to S3. The solution uses the following architecture:

Reference architecture

  1. When an image is uploaded to the source S3 bucket, S3 sends a notification event to an Amazon SQS queue.
  2. The Lambda service polls the SQS queue and invokes an AWS Lambda function when messages are available.
  3. The Lambda function uses Amazon Rekognition to detect faces in the source image. The service returns the coordinates of faces to the function.
  4. After blurring the faces in the source image, the function stores the resulting image in the output S3 bucket.

Deploying the solution

Before deploying the solution, you need:

To deploy:

  1. From a terminal window, clone the GitHub repo:
    git clone https://github.com/aws-samples/serverless-face-blur-service
  2. Change directory:
    cd ./serverless-face-blur-service
  3. Download and install dependencies:
    sam build
  4. Deploy the application to your AWS account:
    sam deploy --guided
  5. During the guided deployment process, enter unique names for the two S3 buckets. These names must be globally unique.

To test the application, upload a JPG file containing at least one face into the source S3 bucket. After a few seconds, the destination bucket contains the output file, with the same name. The output file shows blur content when the faces are detected:

Blurred faces output

How the face blurring Lambda function works

The Lambda function receives messages from the SQS queue when available. These messages contain metadata about the JPG object uploaded to S3:

{
    "Records": [
        {
            "messageId": "e9a12dd2-1234-1234-1234-123456789012",
            "receiptHandle": "AQEBnjT2rUH+kmEXAMPLE",
            "body": "{\"Records\":[{\"eventVersion\":\"2.1\",\"eventSource\":\"aws:s3\",\"awsRegion\":\"us-east-1\",\"eventTime\":\"2021-06-21T19:48:14.418Z\",\"eventName\":\"ObjectCreated:Put\",\"userIdentity\":{\"principalId\":\"AWS:AROA3DTKMEXAMPLE:username\"},\"requestParameters\":{\"sourceIPAddress\":\"73.123.123.123\"},\"responseElements\":{\"x-amz-request-id\":\"AZ39QWJFVEQJW9RBEXAMPLE\",\"x-amz-id-2\":\"MLpNwwQGQtrNai/EXAMPLE\"},\"s3\":{\"s3SchemaVersion\":\"1.0\",\"configurationId\":\"5f37ac0f-1234-1234-82f12343-cbc8faf7a996\",\"bucket\":{\"name\":\"s3-face-blur-source\",\"ownerIdentity\":{\"principalId\":\"EXAMPLE\"},\"arn\":\"arn:aws:s3:::s3-face-blur-source\"},\"object\":{\"key\":\"face.jpg\",\"size\":3541,\"eTag\":\"EXAMPLE\",\"sequencer\":\"123456789\"}}}]}",
            "attributes": {
                "ApproximateReceiveCount": "6",
                "SentTimestamp": "1624304902103",
                "SenderId": "AIDAJHIPREXAMPLE",
                "ApproximateFirstReceiveTimestamp": "1624304902103"
            },
            "messageAttributes": {},
            "md5OfBody": "12345",
            "eventSource": "aws:sqs",
            "eventSourceARN": "arn:aws:sqs:us-east-1:123456789012:s3-lambda-face-blur-S3EventQueue-ABCDEFG01234",
            "awsRegion": "us-east-1"
        }
    ]
}

The body attribute contained a serialized JSON object with an array of records, containing the S3 bucket name and object keys. The Lambda handler in app.js uses the JSON.parse method to create a JSON object from the string:

  const s3Event = JSON.parse(event.Records[0].body)

The handler extracts the bucket and key information. Since the S3 key attribute is URL encoded, it must be decoded before further processing:

const Bucket = s3Event.Records[0].s3.bucket.name
const Key = decodeURIComponent(s3Event.Records[0].s3.object.key.replace(/\+/g, " "))

There are three steps in processing each image: detecting faces in the source image, blurring faces, then storing the output in the destination bucket.

Detecting faces in the source image

The detectFaces.js file contains the detectFaces function. This accepts the bucket name and key as parameters, then uses the AWS SDK for JavaScript to call the Amazon Rekognition service:

const AWS = require('aws-sdk')
AWS.config.region = process.env.AWS_REGION 
const rekognition = new AWS.Rekognition()

const detectFaces = async (Bucket, Name) => {

  const params = {
    Image: {
      S3Object: {
       Bucket,
       Name
      }
     }    
  }

  console.log('detectFaces: ', params)

  try {
    const result = await rekognition.detectFaces(params).promise()
    return result.FaceDetails
  } catch (err) {
    console.error('detectFaces error: ', err)
    return []
  }  
}

The detectFaces method of the Amazon Rekognition API accepts a parameter object defining a reference to the source S3 bucket and key. The service returns a data object with an array called FaceDetails:

{
    "BoundingBox": {
        "Width": 0.20408163964748383,
        "Height": 0.4340078830718994,
        "Left": 0.727995753288269,
        "Top": 0.3109045922756195
    },
    "Landmarks": [
        {
            "Type": "eyeLeft",
            "X": 0.784351646900177,
            "Y": 0.46120116114616394
        },
        {
            "Type": "eyeRight",
            "X": 0.8680923581123352,
            "Y": 0.5227685570716858
        },
        {
            "Type": "mouthLeft",
            "X": 0.7576283812522888,
            "Y": 0.617080807685852
        },
        {
            "Type": "mouthRight",
            "X": 0.8273565769195557,
            "Y": 0.6681531071662903
        },
        {
            "Type": "nose",
            "X": 0.8087539672851562,
            "Y": 0.5677543878555298
        }
    ],
    "Pose": {
        "Roll": 23.821317672729492,
        "Yaw": 1.4818285703659058,
        "Pitch": 2.749311685562134
    },
    "Quality": {
        "Brightness": 83.74250793457031,
        "Sharpness": 89.85481262207031
    },
    "Confidence": 99.9793472290039
}

The Confidence score is the percentage confidence that the image contains a face. This example uses the BoundingBox coordinates to find the location of the face in the image. The response also includes positional data for facial features like the mouth, nose, and eyes.

Blurring faces in the source image

In the blurFaces.js file, the blurFaces function uses the open source GraphicsMagick library to process the source image. The function takes the bucket and key as parameters with the metadata returned by the Amazon Rekognition service:

const AWS = require('aws-sdk')
AWS.config.region = process.env.AWS_REGION 
const s3 = new AWS.S3()
const gm = require('gm').subClass({imageMagick: process.env.localTest})

const blurFaces = async (Bucket, Key, faceDetails) => {

  const object = await s3.getObject({ Bucket, Key }).promise()
  let img = gm(object.Body)

  return new Promise ((resolve, reject) => {
    img.size(function(err, dimensions) {
        if (err) reject(err)
        console.log('Image size', dimensions)

        faceDetails.map((faceDetail) => {
            const box = faceDetail.BoundingBox
            const width  = box.Width * dimensions.width
            const height = box.Height * dimensions.height
            const left = box.Left * dimensions.width
            const top = box.Top * dimensions.height

            img.region(width, height, left, top).blur(0, 70)
        })

        img.toBuffer((err, buffer) => resolve(buffer))
    })
  })
}

The function loads the source object from S3 using the getObject method of the S3 API. In the response, the Body attribute contains a buffer with the image data – this is used to instantiate a ‘gm’ object for processing.

Amazon Rekognition’s bounding box coordinates are percentage-based relative to the size of the image. This code converts these percentages to X- and Y-based coordinates and uses the region method to identify a portion of the image. The blur method uses a Gaussian operator based on the inputs provided. Once the transformation is complete, the function returns a buffer with the new image.

Using GraphicsMagick with Lambda functions

The GraphicsMagick package contains operating system-specific binaries. Depending on the operating system of your development machine, you may install binaries locally that are not compatible with Lambda. The Lambda service uses Amazon Linux 2 (AL2).

To simplify local testing and deployment, the sample application uses Lambda layers to package this library. This open source Lambda layer repo shows how to build, deploy, and test GraphicsMagick as a Lambda layer. It also publishes public layers to help you use the library in your Lambda functions.

When testing this function locally with the test.js script, the GM npm package uses the binaries on the local development machine. When the function is deployed to the Lambda service, the package uses the Lambda layer with the AL2-compatible binaries.

Limiting throughput with Amazon Rekognition

Both S3 and Lambda are highly scalable services and in this example can handle thousands of image uploads a second. In this configuration, S3 sends Event Notifications to an SQS queue each time an object is uploaded. The Lambda function processes events from this queue.

When using downstream services in Lambda functions, it’s important to note the quotas and throughputs in place for those services. This can help avoid throttling errors or overwhelming non-serverless services that may not be able to handle the same level of traffic.

The Amazon Rekognition service sets default transaction per second (TPS) rates for AWS accounts. For the DetectFaces API, the default is between 5-50 TPS depending upon the AWS Region. If you need a higher throughput, you can request an increase in the Service Quotas console.

In the AWS SAM template of the example application, the definition of the Lambda function uses two attributes to control the throughput. The ReservedConcurrentExecutions attribute is set to 1, which prevents the Lambda service from scaling beyond one instance of the function. The BatchSize in event source mapping is also set to 1, so each invocation contains only a single S3 event from the SQS queue:

  BlurFunction:
    Type: AWS::Serverless::Function
    Properties:
      CodeUri: src/
      Handler: app.handler
      Runtime: nodejs14.x
      Timeout: 10
      MemorySize: 2048
      ReservedConcurrentExecutions: 1
      Policies:
        - S3ReadPolicy:
            BucketName: !Ref SourceBucketName
        - S3CrudPolicy:
            BucketName: !Ref DestinationBucketName
        - RekognitionDetectOnlyPolicy: {}
      Environment:
        Variables:
          DestinationBucketName: !Ref DestinationBucketName
      Events:
        MySQSEvent:
          Type: SQS
          Properties:
            Queue: !GetAtt S3EventQueue.Arn
            BatchSize: 1

The combination of these two values means that this function processes images one at a time, regardless of how many images are uploaded to S3. By increasing these values, you can change the scaling behavior and number of messages processed per invocation. This allows you to control the throughput of the number of the messages sent to Amazon Rekognition for processing.

Conclusion

A serverless face blurring service can provide a simpler way to process photos in workloads with large amounts of traffic. This post introduces an example application that blurs faces when images are saved in an S3 bucket. The S3 PutObject event invokes a Lambda function that uses Amazon Rekognition to detect faces and GraphicsMagick to process the images.

This blog post shows how to deploy the example application and walks through the functions that process the images. It explains how to use GraphicsMagick and how to control throughput in the SQS event source mapping.

For more serverless learning resources, visit Serverless Land.

Bringing OAuth 2.0 to Wrangler

Post Syndicated from Mengqi Chen original https://blog.cloudflare.com/wrangler-oauth/

Bringing OAuth 2.0 to Wrangler

Over the course of this summer, I had the incredible opportunity to join the Workers Developer Productivity team and help improve the developer experience of Workers. Today, I’ll talk about my project to implement the OAuth 2.0 login protocol for Wrangler, the Workers command line interface (CLI).

Wrangler needs to be authorized in order to carry out its job. API tokens are one way to authorize Wrangler, but they do not provide the best user experience as the user needs to manually copy and paste their tokens. This is where the OAuth 2.0 protocol comes into play.

Bringing OAuth 2.0 to Wrangler

Wrangler login and OAuth 2.0

Previously, the wrangler login command used API tokens to authenticate Wrangler. However, managing API tokens can sometimes be cumbersome, since you need to go to the Cloudflare dashboard to create or modify a token. By using OAuth 2.0, we can allow users to directly choose permissions or scopes from Wrangler. OAuth 2.0 helps simplify the login process while making it more secure.

OAuth 2.0 is an industry-standard protocol for allowing users to authorize applications without having to share a password. In order to understand this protocol, we need to define some terminology:

  • Resource Owner: an entity capable of granting access to a protected resource. This is the user.
  • Resource Server: the server hosting the protected resource. This is the Cloudflare API.
  • Client: an application making protected resource requests on behalf of the resource owner and with its authorization. This is Wrangler, making API calls on the behalf of the user.
  • Authorization Server: The server issuing access tokens to the client after successfully authenticating the resource owner and obtaining authorization. This is our OAuth 2.0 service provider.

The protocol has several flows, but they all share the same objective. The resource owner needs to explicitly grant permission to the client, which can then receive an access token from the authorization server. With this access token, the client is authorized to access protected resources stored on the resource server.

Authorization Code Flow

Among the different types of flows that make up the OAuth 2.0 protocol, Wrangler implements the Authorization Code Flow with PKCE challenges. Let’s take a look at what this entails!

Bringing OAuth 2.0 to Wrangler

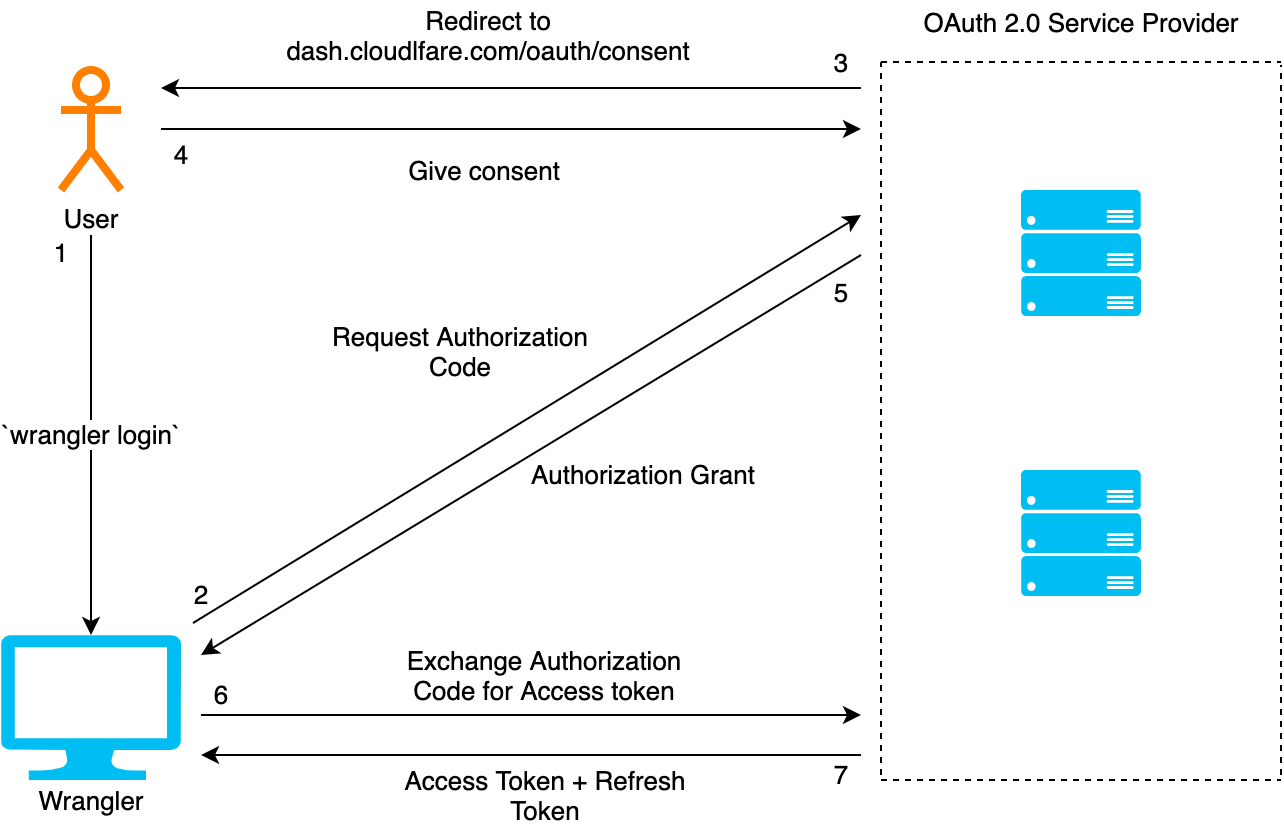
When running wrangler login, the user is first prompted to log in to the Cloudflare dashboard. Once they are logged in, they are redirected to an authorization page, where they can decide to grant or deny authorization to Wrangler. If authorization is granted, Wrangler receives an authorization grant from the OAuth service provider. Once received, Wrangler exchanges the authorization grant for an access token and a refresh token. At this point, Wrangler stores both of these tokens on disk and uses the access token to make authorized API calls. Since the access token is short-lived, refresh tokens are used to update an expired access token. Throughout this flow, Wrangler and the OAuth service provider also use additional measures to verify the identity of each other, as later described in the Security section of this blog.

Use what you need, only when you need it

In addition to providing a smoother developer experience, the new wrangler login also allows a user to specify which scopes they need. For example, if you would like to have an OAuth token with just account and user read permissions, you can do so by running:

wrangler login --scopes account:read user:read

For more information about the currently available scopes, you can run wrangler login --scopes-list or visit the Wrangler login documentation.

Revoke access at any time

The OAuth 2.0 protocol also defines a flow to revoke authorization from Wrangler. In this workflow, a user can deny Wrangler access to protected resources by simply using the command wrangler logout. This command will make a request to the OAuth 2.0 service provider and invalidate the refresh token, which will automatically invalidate the associated access token.

Security

The OAuth integration also brings improved security by using Cross-Site Request Forgery (CSRF) states, Proof Key for Code Exchange (PKCE) challenges, and short-lived access tokens.

Throughout the first part of the wrangler login flow, Wrangler needs to request an authorization grant. In order to avoid the possibility of a forged response, Wrangler includes a CSRF state in the parameters of the authorization code request. The CSRF state is a unique randomly generated value, which is used to confirm the response received from the OAuth service provider. In addition to the CSRF state, Wrangler will also include a PKCE code_challenge. This code_challenge will be used by the OAuth service provider to verify that Wrangler is the same application when exchanging the authorization grant for an access token. The PKCE challenge is a protection against stolen authorization grants. As the OAuth service provider will reject access token requests if it cannot verify the PKCE code_challenge.

The final way the new OAuth workflow improves security is by making access tokens short-lived. In this sense, if an access token gets stolen, how can we notify the resource server that the access token should not be trusted? Well, we can’t really. So, there are three options: 1) wait until the expiration time; 2) use the refresh token to get a new access token, which invalidates the previous access token; or 3) invalidate both refresh and access tokens. This provides us with three ways to protect resources from bad actors with stolen access tokens.

What’s next

OAuth 2.0 integration is now available in the 1.19.3 version release of Wrangler. Try it out and let us know your experience. If you prefer the API tokens or global API keys, no worries. You can still access them using the wrangler config command.

I would also like to thank the Workers team and other Cloudflare teams for the incredible internship experience. This opportunity gave me a glimpse into what industry software development looks like, and the opportunity to dive deep into a meaningful project. I enjoyed the responsiveness and teamwork during the internship, making this a great summer.

Managing federated schema with AWS Lambda and Amazon S3

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/managing-federated-schema-with-aws-lambda-and-amazon-s3/

This post is written by Krzysztof Lis, Senior Software Development Engineer, IMDb.

GraphQL schema management is one of the biggest challenges in the federated setup. IMDb has 19 subgraphs (graphlets) – each of them owns and publishes a part of the schema as a part of an independent CI/CD pipeline.

To manage federated schema effectively, IMDb introduced a component called Schema Manager. This is responsible for fetching the latest schema changes and validating them before publishing it to the Gateway.

Part 1 presents the migration from a monolithic REST API to a federated GraphQL (GQL) endpoint running on AWS Lambda. This post focuses on schema management in federated GQL systems. It shows the challenges that the teams faced when designing this component and how we addressed them. It also shares best practices and processes for schema management, based on our experience.

Comparing monolithic and federated GQL schema

In the standard, monolithic implementation of GQL, there is a single file used to manage the whole schema. This makes it easier to ensure that there are no conflicts between the new changes and the earlier schema. Everything can be validated at the build time and there is no risk that external changes break the endpoint during runtime.

This is not true for the federated GQL endpoint. The gateway fetches service definitions from the graphlets on runtime and composes the overall schema. If any of the graphlets introduces a breaking change, the gateway fails to compose the schema and won’t be able to serve the requests.

The more graphlets we federate to, the higher the risk of introducing a breaking change. In enterprise scale systems, you need a component that protects the production environment from potential downtime. It must notify graphlet owners that they are about to introduce a breaking change, preferably during development before releasing the change.

Federated schema challenges

There are other aspects of handling federated schema to consider. If you use AWS Lambda, the default schema composition increases the gateway startup time, which impacts the endpoint’s performance. If any of the declared graphlets are unavailable at the time of schema composition, there may be gateway downtime or at least an incomplete overall schema. If schemas are pre-validated and stored in a highly available store such as Amazon S3, you mitigate both of these issues.

Another challenge is schema consistency. Ideally, you want to propagate the changes to the gateway in a timely manner after a schema change is published. You also need to consider handling field deprecation and field transfer across graphlets (change of ownership). To catch potential errors early, the system should support dry-run-like functionality that will allow developers to validate changes against the current schema during the development stage.

The Schema Manager

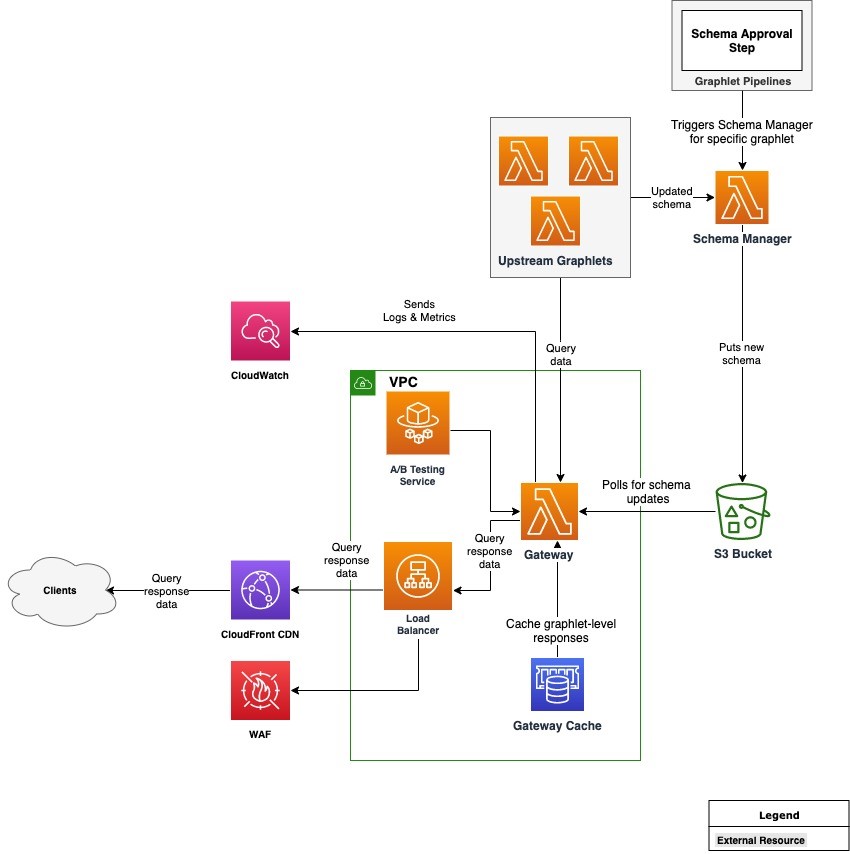
Schema Manager

To mitigate these challenges, the Gateway/Platform team introduces a Schema Manager component to the workload. Whenever there’s a deployment in any of the graphlet pipelines, the schema validation process is triggered.

Schema Manager fetches the most recent sub-schemas from all the graphlets and attempts to compose an overall schema. If there are no errors and conflicts, a change is approved and can be safely promoted to production.

In the case of a validation failure, the breaking change is blocked in the graphlet deployment pipeline and the owning team must resolve the issue before they can proceed with the change. Deployments of graphlet code changes also depend on this approval step, so there is no risk that schema and backend logic can get out of sync, when the approval step blocks the schema change.

Integration with the Gateway

To handle versioning of the composed schema, a manifest file stores the locations of the latest approved set of graphlet schemas. The manifest is a JSON file mapping the name of the graphlet to the S3 key of the schema file, in addition to the endpoint of the graphlet service.

The file name of each graphlet schema is a hash of the schema. The Schema Manager pulls the current manifest and uses the hash of the validated schema to determine if it has changed:

{
   "graphlets": {
     "graphletOne": {
        "schemaPath": "graphletOne/1a3121746e75aafb3ca9cccb94f23d89",
        "endpoint": "arn:aws:lambda:us-east-1:123456789:function:GraphletOne"
     },
     "graphletTwo": { 
        "schemaPath": "graphletTwo/213362c3684c89160a9b2f40cd8f191a",
        "endpoint": "arn:aws:lambda:us-east-1:123456789:function:GraphletTwo"
     },
     ...
  }
}

Based on these details, the Gateway fetches the graphlet schemas from S3 as part of service startup and stores them in the in-memory cache. It later polls for the updates every 5 minutes.

Using S3 as the schema store addresses the latency, availability and validation concerns of fetching schemas directly from the graphlets on runtime.

Eventual schema consistency

Since there are multiple graphlets that can be updated at the same time, there is no guarantee that one schema validation workflow will not overwrite the results of another.

For example:

  1. SchemaUpdater 1 runs for graphlet A.
  2. SchemaUpdater 2 runs for graphlet B.
  3. SchemaUpdater 1 pulls the manifest v1.
  4. SchemaUpdater 2 pulls the manifest v1.
  5. SchemaUpdater 1 uploads manifest v2 with change to graphlet A
  6. SchemaUpdater 2 uploads manifest v3 that overwrites the changes in v2. Contains only changes to graphlet B.

This is not a critical issue because no matter which version of the manifest wins in this scenario both manifests represent a valid schema and the gateway does not have any issues. When SchemaUpdater is run for graphlet A again, it sees that the current manifest does not contain the changes uploaded before, so it uploads again.

To reduce the risk of schema inconsistency, Schema Manager polls for schema changes every 15 minutes and the Gateway polls every 5 minutes.

Local schema development

Schema validation runs automatically for any graphlet change as a part of deployment pipelines. However, that feedback loop happens too late for an efficient schema development cycle. To reduce friction, the team uses a tool that performs this validation step without publishing any changes. Instead, it would output the results of the validation to the developer.

Schema validation

The Schema Validator script can be added as a dependency to any of the graphlets. It fetches graphlet’s schema definition described in Schema Definition Language (SDL) and passes it as payload to Schema Manager. It performs the full schema validation and returns any validation errors (or success codes) to the user.

Best practices for federated schema development

Schema Manager addresses the most critical challenges that come from federated schema development. However, there are other issues when organizing work processes at your organization.

It is crucial for long term maintainability of the federated schema to keep a high-quality bar for the incoming schema changes. Since there are multiple owners of sub-schemas, it’s good to keep a communication channel between the graphlet teams so that they can provide feedback for planned schema changes.

It is also good to extract common parts of the graph to a shared library and generate typings and the resolvers. This lets the graphlet developers benefit from strongly typed code. We use open-source libraries to do this.

Conclusion

Schema Management is a non-trivial challenge in federated GQL systems. The highest risk to your system availability comes with the potential of introducing breaking schema change by one of the graphlets. Your system cannot serve any requests after that. There is the problem of the delayed feedback loop for the engineers working on schema changes and the impact of schema composition during runtime on the service latency.

IMDb addresses these issues with a Schema Manager component running on Lambda, using S3 as the schema store. We have put guardrails in our deployment pipelines to ensure that no breaking change is deployed to production. Our graphlet teams are using common schema libraries with automatically generated typings and review the planned schema changes during schema working group meetings to streamline the development process.

These factors enable us to have stable and highly maintainable federated graphs, with automated change management. Next, our solution must provide mechanisms to prevent still-in-use fields from getting deleted and to allow schema changes coordinated between multiple graphlets. There are still plenty of interesting challenges to solve at IMDb.

For more serverless learning resources, visit Serverless Land.

Getting started with testing serverless applications

Post Syndicated from Talia Nassi original https://aws.amazon.com/blogs/compute/getting-started-with-testing-serverless-applications/

Testing is an essential step in the software development lifecycle. Through the different types of tests, you validate user experience, performance, and detect bugs in your code. Features should not be considered done until all of the corresponding tests are written.

The distributed nature of serverless architectures separates your application logic from other concerns like state management, request routing, workflow orchestration, and queue polling.

In this post, I cover the three main types of testing developers do when building applications. I also go through what changes and what stays the same when building serverless applications with AWS Lambda, in addition to the challenges of testing serverless applications.

The challenges of testing serverless applications

To test your code fully using managed services, you need to emulate the cloud environment on your local machine. However, this is usually not practical.

Secondly, using many managed services for event-driven architecture means you must also account for external resources like queues, database tables, and event buses. This means you write more integration tests than unit tests, altering the standard testing pyramid. Building more integration tests can impact the maintenance of your tests or slow your testing speed.

Lastly, with synchronous workloads, such as a traditional web service, you make a request and assert on the response. The test doesn’t need to do anything special because the thread is blocked until the response returns.

However, in the case of event-driven architectures, state changes are driven by events flowing from one resource to another. Your tests must detect side effects in downstream components and these might not be immediate. This means that the tests must tolerate asynchronous behaviors, which can make for more complicated and slower-running tests.

Unit testing

Unit tests validate individual units of your code, independent from any other components. Unit tests check the smallest unit of functionality and should only have one reason to fail – the unit is not correctly implemented.

Unit tests generally cover the smallest units of functionality although the size of each unit can vary. For example, a number of functions may provide a coherent piece of behavior and you may want to test them as a single unit. In this case, your unit test might call an entry-point function that invokes several others to do its job. You test these functions together as a single unit.

unit testing

Integration Testing

One good practice to test how services interact with each other is to write integration tests that mock the behavior of your services in the cloud.

The point of integration tests is to make sure that two components of your application work together properly. Integration tests are important in serverless applications because they rely heavily on integrations of different services. Unless you are testing in production, the most efficient way to run automated integration tests is to emulate your services in the cloud.

This can be done with tools like moto. Moto mocks calls to AWS automatically without requiring any other dependencies. Another useful tool is localstack. Localstack allows you to mock certain AWS service APIs on your local machine that you can use for testing the integration of two or more services.

You can also configure test events and manually test directly from the Lambda console. Remember that when you test a Lambda function, you are not only testing the business logic. You must also mock its payload and call a function invoke. There are over 200 event sources that can trigger Lambda functions. Each service has its own unique event format, and contains data about the resource or request that invoked the function. Find the full list of test events in the AWS documentation.

To configure a test event for AWS Lambda:

  1. Navigate to the Lambda console and choose the function. From the Test dropdown, choose Configure Test Event.step 1
  2. Choose Create a new Test Event and select the template for the service you want to act as the trigger for your Lambda function. In this example, you choose Amazon DynamoDB Update.
    step 2
  3. Save the test event and choose Test in the Code source section. Each user can create up to 10 test events per function. Those test events are private to you. Lambda runs the function on your behalf. The function handler receives and then processes the sample event.
    step 3
  4. The Execution result shows the execution status as succeeded.

End-to-end testing

When testing your serverless applications end-to-end, it’s important to understand your user and data flows. The most important business-critical flows of your software are what should be tested end-to-end in your UI.

From a business perspective, these should be the most valuable user and data flows that occur in your product. Another resource to utilize is data from your customers. From your analytics platform, find the actions that users are doing the most in production.

End-to-end tests should be running in your build pipeline and act as blockers if one of them fails. They should also be updated as new features are added to your product.

The testing pyramid

testing pyramid

The standard testing pyramid above on the left indicates that systems should have more unit tests than any other type of test, then a medium number of integration tests, and the least number of end-to-end tests.

However, when testing serverless applications, this standard shifts to a hexagonal structure on the right because it’s mostly made up of two or more AWS services talking to each other. You can mock out those integrations with tools such as moto or localstack.

Add automated tests to your CI/CD pipeline

As serverless applications scale, having automated tests is essential in getting fast feedback on the current state of your product. It is not scalable to test everything manually, so investing in an automation tool to run your tests is essential.

All of the tests in your build pipeline, including unit, integration, and end-to-end tests should be blocking in your CI/CD pipeline. This means if one of them fails, it should block the promotion of that code into production. And remember – there’s no such thing as a flakey test. Either the test does what it’s supposed to do, or it doesn’t.

Narrowly scope your tests

Testing asynchronous processes can be tricky. Not only must you monitor different parts of your system, you also need to know when to stop waiting and end the test. When there are multiple asynchronous steps, the delays add up to a longer-running test. It’s also more difficult to estimate how long we should wait before ending. There are two approaches to mitigate these issues.

Firstly, write separate, more narrowly-scoped tests over each asynchronous step. This limits the possible causes of asynchronous test failure you need to investigate. Also, with fewer asynchronous steps, these tests will run quicker and it will be easier to estimate how long to wait before timing out.

Secondly, verify as much of your system as possible using synchronous tests. Then, you only need asynchronous tests to verify residual concerns that aren’t already covered. Synchronous tests are also easier to diagnose when they fail, so you want to catch as many issues with them as possible before running your asynchronous tests.

Conclusion

In this blog post, you learn the three types of testing – unit testing, integration testing, and end-to-end testing. Then you learn how to configure test events with Lambda. I then cover the shift from the standard testing pyramid to the hexagonal testing pyramid for serverless, and why more integration tests are necessary. Then you learn a few best practices to keep in mind for getting started with testing your serverless applications.

For more information on serverless, head to Serverless Land.

Building federated GraphQL on AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/building-federated-graphql-on-aws-lambda/

This post is written by Krzysztof Lis, Senior Software Development Engineer, IMDb.

IMDb is the world’s most popular source for movie, TV, and celebrity content. It deals with a complex business domain including movies, shows, celebrities, industry professionals, events, and a distributed ownership model. There are clear boundaries between systems and data owned by various teams.

Historically, IMDb uses a monolithic REST gateway system that serves clients. Over the years, it has become challenging to manage effectively. There are thousands of files, business logic that lacks clear ownership, and unreliable integration tests tied to the data. To fix this, the team used GraphQL (GQL). This is a query language for APIs that lets you request only the data that you need and a runtime for fulfilling those queries with your existing data.

It’s common to implement this protocol by creating a monolithic service that hosts the complete schema and resolves all fields requested by the client. It is good for applications with a relatively small domain and clear, single-threaded ownership. IMDb chose the federated approach, that allows us to federate GQL requests to all existing data teams. This post shows how to build federated GraphQL on AWS Lambda.

Overview

This article covers migration from a monolithic REST API and monolithic frontend to a federated backend system powering a modern frontend. It enumerates challenges in the earlier system and explains why federated GraphQL addresses these problems.

I present the architecture overview and describe the decisions made when designing the new system. I also present our experiences with developing and running high-traffic and high-visibility pages on the new endpoint – improvement in IMDb’s ownership model, development lifecycle, in addition to ease of scaling.

Comparing GraphQL with federated GraphQL

Comparing GraphQL with federated GraphQL

Federated GraphQL allows you to combine GraphQLs APIs from multiple microservices into a single API. Clients can make a single request and fetch data from multiple sources, including joining across data sources, without additional support from the source services.

This is an example schema fragment:

type TitleQuote {
  "Quote ID"
  id: ID!
  "Is this quote a spoiler?"
  isSpoiler: Boolean!
  "The lines that make up this quote"
  lines: [TitleQuoteLine!]!
  "Votes from users about this quote..."
  interestScore: InterestScore!
  "The language of this quote"
  language: DisplayableLanguage!
}
"A specific line in the Title Quote. Can be a verbal line with characters speaking or stage directions"
type TitleQuoteLine {
  "The characters who speak this line, e.g.  'Rick'. Not required: a line may be non-verbal"
  characters: [TitleQuoteCharacter!]
  "The body of the quotation line, e.g 'Here's looking at you kid. '.  Not required: you may have stage directions with no dialogue."
  text: String
  "Stage direction, e.g. 'Rick gently places his hand under her chin and raises it so their eyes meet'. Not required."
  stageDirection: String
}

This is an example monolithic query: “Get the 2 top quotes from The A-Team (title identifier: tt0084967)”:

{ 
  title(id:"tt0084967"){ 
    quotes(first:2){ 
      lines { text } 
    } 
  }
}

Here is an example response:

{ 
  "data": { 
    "title": { 
      "quotes": { 
        "lines": [
          { 
            "text": "I love it when a plan comes together!"
          },
          {
            "text": "10 years ago a crack commando unit was sent to prison by a military court for a crime they didn't commit..."
          }
        ]
      } 
    }
  }
}

This is an example federated query: “What is Jackie Chan (id nm0000329) known for? Get the text, rating and image for each title”

{
  name(id: "nm0000329") {
    knownFor(first: 4) {
      title {
        titleText {
          text
        }
        ratingsSummary {
          aggregateRating
        }
        primaryImage {
          url
        }
      }
    }
  }
}

The monolithic example fetches quotes from a single service. In the federated example, knownFor, titleText, ratingsSummary, primaryImage are fetched transparently by the gateway from separate services. IMDb federates the requests across 19 graphlets, which are transparent to the clients that call the gateway.

Architecture overview

Architecture overview

IMDb supports three channels for users: website, iOS, and Android apps. Each of the channels can request data from a single federated GraphQL gateway, which federates the request to multiple graphlets (sub-graphs). Each of the invoked graphlets returns a partial response, which the gateway merges with responses returned by other graphlets. The client receives only the data that they requested, in the shape specified in the query. This can be especially useful when the developers must be conscious of network usage (for example, over mobile networks).

This is the architecture diagram:

Architecture diagram

There are two core components in the architecture: the Gateway and Schema Manager, which run on Lambda. The Gateway is a Node.js-based Lambda function that is built on top of open-source Apollo Gateway code. It is customized with code responsible predominantly for handling authentication, caching, metrics, and logging.

Other noteworthy components are Upstream Graphlets and an A/B Testing Service that enables A/B tests in the graph. The Gateway is connected to an Application Load Balancer, which is protected by AWS WAF and fronted by Amazon CloudFront as our CDN layer. This uses Amazon ElastiCache with Redis as the engine to cache partial responses coming from graphlets. All logs and metrics generated by the system are collected in Amazon CloudWatch.

Choosing the compute platform

This uses Lambda, since it scales on demand. IMDb uses Lambda’s Provisioned Concurrency to reduce cold start latency. The infrastructure is abstracted away so there is no need for us to manage our own capacity and handle patches.

Additionally, Application Load Balancer (ALB) has support for directing HTTP traffic to Lambda. This is an alternative to API Gateway. The workload does not need many of the features that API Gateway provides, since the gateway has a single endpoint, making ALB a better choice. ALB also supports AWS WAF.

Using Lambda, the team designed a way to fetch schema updates without needing to fetch the schema with every request. This is addressed with the Schema Manager component. This component improves latency and improves the overall customer experience.

Integration with legacy data services

The main purpose of the federated GQL migration is to deprecate a monolithic service that aggregates data from multiple backend services before sending it to the clients. Some of the data in the federated graph comes from brand new graphlets that are developed with the new system in mind.

However, much of the data powering the GQL endpoint is sourced from the existing backend services. One benefit of running on Lambda is the flexibility to choose the runtime environment that works best with the underlying data sources and data services.

For the graphlets relying on the legacy services, IMDb uses lightweight Java Lambda functions using provided client libraries written in Java. They connect to legacy backends via AWS PrivateLink, fetch the data, and shape it in the format expected by the GQL request. For the modern graphlets, we recommend the graphlet teams to explore Node.js as the first option due to improved performance and ease of development.

Caching

The gateway supports two caching modes for graphlets: static and dynamic. Static caching allows graphlet owners to specify a default TTL for responses returned by a graphlet. Dynamic caching calculates TTL based on a custom caching extension returned with the partial response. It allows graphlet owners to decide on the optimal TTL for content returned by their graphlet. For example, it can be 24 hours for queries containing only static text.

Permissions

Each of the graphlets runs in a separate AWS account. The graphlet accounts grant the gateway AWS account (as AWS principal) invoke permissions on the graphlet Lambda function. This uses a cross-account IAM role in the development environment that is assumed by stacks deployed in engineers’ personal accounts.

Experience with developing on federated GraphQL

The migration to federated GraphQL delivered on expected results. We moved the business logic closer to the teams that have the right expertise – the graphlet teams. At the same time, a dedicated platform team owns and develops the core technical pieces of the ecosystem. This includes the Gateway and Schema Manager, in addition to the common libraries and CDK constructs that can be reused by the graphlet teams. As a result, there is a clear ownership structure, which is aligned with the way IMDb teams are organized.

In terms of operational excellence of the platform team, this reduced support tickets related to business logic. Previously, these were routed to an appropriate data service team with a delay. Integration tests are now stable and independent from underlying data, which increases our confidence in the Continuous Deployment process. It also eliminates changing data as a potential root cause for failing tests and blocked pipelines.

The graphlet teams now have full ownership of the data available in the graph. They own the partial schema and the resolvers that provide data for that part of the graph. Since they have the most expertise in that area, the potential issues are identified early on. This leads to a better customer experience and overall health of the system.

The web and app developers groups are also impacted by the migration. The learning curve was aided by tools like GraphQL Playground and Apollo Client. The teams covered the learning gap quickly and started delivering new features.

One of the main pages at IMDb.com is the Title Page (for example, Shutter Island). This was successfully migrated to use the new GQL endpoint. This proves that the new, serverless federated system can serve production traffic at over 10,000 TPS.

Conclusion

A single, highly discoverable, and well-documented backend endpoint enabled our clients to experiment with the data available in the graph. We were able to clean up the backend API layer, introduce clear ownership boundaries, and give our client powerful tools to speed up their development cycle.

The infrastructure uses Lambda to remove the burden of managing, patching, and scaling our EC2 fleets. The team dedicated this time to work on features and operational excellence of our systems.

Part two will cover how IMDb manages the federated schema and the guardrails used to ensure high availability of the federated GraphQL endpoint.

For more serverless learning resources, visit Serverless Land.

How The Mill Adventure Implemented Event Sourcing at Scale Using DynamoDB

Post Syndicated from Uri Segev original https://aws.amazon.com/blogs/architecture/how-the-mill-adventure-implemented-event-sourcing-at-scale-using-dynamodb/

This post was co-written by Joao Dias, Chief Architect at The Mill Adventure and Uri Segev, Principal Serverless Solutions Architect at AWS

The Mill Adventure provides a complete gaming platform, including licenses and operations, for rapid deployment and success in online gaming. It underpins every aspect of the process so that you can focus on telling your story to your audience while the team makes everything else work perfectly.

In this blog post, we demonstrate how The Mill Adventure implemented event sourcing at scale using Amazon DynamoDB and Serverless on AWS technologies. By partnering with AWS, The Mill Adventure reduced their costs, and they are able to maintain operations and scale their solution to suit their needs without their intervention.

What is event sourcing?

Event sourcing captures an entity’s state (such as a transaction or a user) as a sequence of state-changing events. Whenever the state changes, a new event is appended to the sequence of events using an atomic operation.

The system persists these events in an event store, which is a database of events. The store supports adding and retrieving the state events. The system reconstructs the entity’s state by reading the events from the event store and replaying them. Because the store is immutable (meaning these events are saved in the event store forever) the entity’s state can be recreated up to a particular version or date and have accurate historical values.

Why use event sourcing?

Event sourcing provides many advantages, that include (but are not limited to) the following:

  • Audit trail: Events are immutable and provide a history of what has taken place in the system. This means it’s not only providing the current state, but how it got there.
  • Time travel: By persisting a sequence of events, it is relatively easy to determine the state of the system at any point in time by aggregating the events within that time period. This provides you the ability to answer historical questions about the state of the system.
  • Performance: Events are simple and immutable and only require an append operation. The event store should be optimized to handle high-performance writes.
  • Scalability: Storing events avoids the complications associated with saving complex domain aggregates to relational databases, which allows more flexibility for scaling.

Event-driven architectures

Event sourcing is also related to event-driven architectures. Every event that changes an entity’s state can also be used to notify other components about the change. In event-driven architectures, we use event routers to distribute the events to interested components.

The event router has three main functions:

  1. Decouple the event producers from the event consumers: The producers don’t know who the consumers are, and they do not need to change when new consumers are added or removed.
  2. Fan out: Event routers are capable of distributing events to multiple subscribers.
  3. Filtering: Event routers send each subscriber only the events they are interested in. This saves on the number of events that consumers need to process; therefore, it reduces the cost of the consumers.

How did The Mill Adventure implement event sourcing?

The Mill Adventure uses DynamoDB tables as their object store. Each event is a new item in the table. The DynamoDB table model for an event sourced system is quite simple, as follows:

Field Type Description
id PK The object identifier
version SK The event sequence number
eventdata The event data itself, in other words, the change to the object’s state

All events for the same object have the same id. Thus, you can retrieve them using a single read request.

When a component modifies the state of an object, it first determines the sequence number for the new event by reading the current state from the table (in other words, the sequence of events for that object). It then attempts to write a new item to the table that represents the change to the object’s state. The item is written using DynamoDB’s conditional write. This ensures that there are no other changes to the same object happening at the same time. If the write failed due to a condition not met error, it will start over.

An additional benefit of using DynamoDB as the event store is DynamoDB Streams, which is used to deliver events about changes in tables. These events can be used by event-driven applications so they will know about the different objects’ change of state.

How does it work?

Let’s use an example of a business entity, such as a user. When a user is created, the system creates a UserCreated event with the initial user data (like user name, address, etc.). The system then persists this event to the DynamoDB event store using a conditional write. This makes sure that the event is only written once and that the version numbers are sequential.

Then the user address gets updated, so again, the system creates a UserUpdated event with the new address and persists it.

When the system needs the user’s current state, for example, to show it in back-office application, the system loads all the events for the given user identifier from the store. For each one of them, it invokes a mutation function that recreates the latest state. Given the following items in the database:

  • Event 1: UserCreated(name: The Mill, address: Malta)
  • Event 2: UserUpdated(address: World)

You can imagine how each mutator function for those events would look like, which then produce the latest state:

{ 
"name": "The Mill", 
"address": "World" 
}

A business state like a bank statement can have a large number of events. To optimize loading, the system periodically saves a snapshot of the current state. To reconstruct the current state, the application finds the most recent snapshot and the events that have occurred since that snapshot. As a result, there are fewer events to replay.

Architecture

The Mill Adventure architecture for an event source system using AWS components is straightforward. The architecture is fully serverless, as such, it only uses AWS Lambda functions for compute. Lambda functions produce the state-changing events that are written to the database.

Other Lambda functions, when they retrieve an object’s state, will read the events from the database and calculate the current state by replaying the events.

Finally, interested functions will be notified about the changes by subscribing to the event bus. Then they perform their business logic, like updating state projections or publishing to WebSocket APIs. These functions use DynamoDB streams as the event bus to handle messages as shows in Figure 1.

Event sourcing architecture

Figure 1. Event sourcing architecture

Figure 1 is not completely accurate due to a limitation of DynamoDB Streams, which can only support up to two subscribers.

Because The Mill Adventure has many microservices that are interested in these events, they have a single function that gets invoked from the stream and sends the events to other event routers. These fan out to a large number of subscribers such as Amazon EventBridge, Amazon Simple Notification Service (Amazon SNS), or maybe even Amazon Kinesis Data Streams for some use cases.

Any service in the system could be listening to these events being created via the DynamoDB stream and distributed via the event router and act on them. For example, publishing a WebSocket API notification or prompting a contact update in a third-party service.

Conclusion

In this blog post, we showed how The Mill Adventure uses serverless technologies like DynamoDB and Lambda functions to implement an event-driven event sourcing system.

An event sourced system can be difficult to scale, but using DynamoDB as the event store resolved this issue. It can also be difficult to produce consistent snapshots and Command Query Responsibility Segregation (CQRS) views, but using DynamoDB streams for distributing the events made it relatively easy.

By partnering with AWS, The Mill Adventure created a sports/casino platform to be proud of. It provides high quality data and performance without having servers, they only pay for what they use, and their workload can scale up and down as needed.

Building a serverless GIF generator with AWS Lambda: Part 2

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/building-a-serverless-gif-generator-with-aws-lambda-part-2/

In part 1 of this blog post, I explain how a GIF generation service can support a front-end application for video streaming. I compare the performance of a server-based and serverless approach and show how parallelization can significantly improve processing time. I introduce an example application and I walk through the solution architecture.

In this post, I explain the scaling behavior of the example application and consider alternative approaches. I also look at how to manage memory, temporary space, and files in this type of workload. Finally, I discuss the cost of this approach and how to determine if a workload can use parallelization.

To set up the example, visit the GitHub repo and follow the instructions in the README.md file. The example application uses the AWS Serverless Application Model (AWS SAM), enabling you to deploy the application more easily in your own AWS account. This walkthrough creates some resources covered in the AWS Free Tier but others incur cost.

Scaling up the AWS Lambda workers with Amazon EventBridge

There are two AWS Lambda functions in the example application. The first detects the length of the source video and then generates batches of events containing start and end times. These events are put onto the Amazon EventBridge default event bus.

An EventBridge rule matches the events and invokes the second Lambda function. This second function receives the events, which have the following structure:

{
    "version": "0",
    "id": "06a1596a-1234-1234-1234-abc1234567",
    "detail-type": "newVideoCreated",
    "source": "custom.gifGenerator",
    "account": "123456789012",
    "time": "2021-0-17T11:36:38Z",
    "region": "us-east-1",
    "resources": [],
    "detail": {
        "key": "long.mp4",
        "start": 2250,
        "end": 2279,
        "length": 3294.024,
        "tsCreated": 1623929798333
    }
}

The detail attribute contains the unique start and end time for the slice of work. Each Lambda invocation receives a different start and end time and works on a 30-second snippet of the whole video. The function then uses FFMPEG to download the original video from the source Amazon S3 bucket and perform the processing for its allocated time slice.

The EventBridge rule matches events and invokes the target Lambda function asynchronously. The Lambda service scales up the number of execution environments in response to the number of events:

Solution architecture

The first function produces batches of events almost simultaneously but the worker function takes several seconds to process a single request. If there is no existing environment available to handle the request, the Lambda scales up to process the work. As a result, you often see a high level of concurrency when running this application, which is how parallelization is achieved:

CloudWatch metrics

Lambda continues to scale up until it reaches the initial burst concurrency quotas in the current AWS Region. These quotas are between 500 and 3000 execution environments per minute initially. After the initial burst, concurrency scales by an additional 500 instances per minute.

If the number of events is higher, Lambda responds to EventBridge with a throttling error. The EventBridge service retries the events with exponential backoff for 24 hours. Once Lambda is scaled sufficiently or existing execution environments become available, the events are then processed.

This means that under exceptional levels of heavy load, this retry pattern adds latency to the overall GIF generation task. To manage this, you can use Provisioned Concurrency to ensure that more execution environments are available during periods of very high load.

Alternative ways to scale the Lambda workers

The asynchronous invocation mode for Lambda allows you to scale up worker Lambda functions quickly. This is the mode used by EventBridge when Lambda functions are defined as targets in rules. The other benefit of using EventBridge to decouple the two functions in this example is extensibility. Currently, the events have only a single consumer. However, you can add new capabilities to this application by building new event consumers, without changing the producer logic. Note that using EventBridge in this architecture costs $1 per million events put onto the bus (this cost varies by Region). Delivery to targets in EventBridge is free.

This design could similarly use Amazon SNS, which also invokes consuming Lambda functions asynchronously. This costs $0.50 per million messages and delivery to Lambda functions is free (this cost varies by Region). Depending on if you use EventBridge capabilities, SNS may be a better choice for decoupling the two Lambda functions.

Alternatively, the first Lambda function could invoke the second function by using the invoke method of the Lambda API. By using the AWS SDK for JavaScript, one Lambda function can invoke another directly from the handler code. When the InvocationType is set to ‘Event’, this invocation occurs asynchronously. That means that the calling function does not wait for the target function to finish before continuing.

This direct integration between two Lambda services is the lowest latency alternative. However, this limits the extensibility of the solution in the future without modifying code.

Managing memory, temp space, and files

You can configure the memory for a Lambda function up to 10,240 MB. However, the temporary storage available in /tmp is always 512 MB, regardless of memory. Increasing the memory allocation proportionally increases the amount of virtual CPU and network bandwidth available to the function. To learn more about how this works in detail, watch Optimizing Lambda performance for your serverless applications.

The original video files used in this workload may be several gigabytes in size. Since these may be larger than the /tmp space available, the code is designed to keep the movie file in memory. As a result, this solution works for any length of movie that can fit into the 10 GB memory limit.

The FFMPEG application expects to work with local file systems and is not designed to work with object stores like Amazon S3. It can also read video files from HTTP endpoints, so the example application loads the S3 object over HTTPS instead of downloading the file and using the /tmp space. To achieve this, the code uses the getSignedUrl method of the S3 class in the SDK:

 	// Configure S3
 	const AWS = require('aws-sdk')
 	AWS.config.update({ region: process.env.AWS_REGION })
 	const s3 = new AWS.S3({ apiVersion: '2006-03-01' }) 

 	// Get signed URL for source object
	const params = {
		Bucket: record.s3.bucket.name, 
		Key: record.s3.object.key, 
		Expires: 300
	}
	const url = s3.getSignedUrl('getObject', params)

The resulting URL contains credentials to download the S3 object over HTTPs. The Expires attributes in the parameters determines how long the credentials are valid for. The Lambda function calling this method must have appropriate IAM permissions for the target S3 bucket.

The GIF generation Lambda function stores the output GIF and JPG in the /tmp storage space. Since the function can be reused by subsequent invocations, it’s important to delete these temporary files before each invocation ends. This prevents the function from using all of the /tmp space available. This is handled by the tmpCleanup function:

const fs = require('fs')
const path = require('path')
const directory = '/tmp/'

// Deletes all files in a directory
const tmpCleanup = async () => {
    console.log('Starting tmpCleanup')
    fs.readdir(directory, (err, files) => {
        return new Promise((resolve, reject) => {
            if (err) reject(err)

            console.log('Deleting: ', files)                
            for (const file of files) {
                const fullPath = path.join(directory, file)
                fs.unlink(fullPath, err => {
                    if (err) reject (err)
                })
            }
            resolve()
        })
    })
}

When the GenerateFrames parameter is set to true in the AWS SAM template, the worker function generates one frame per second of video. For longer videos, this results in a significant number of files. Since one of the dimensions of S3 pricing is the number of PUTs, this function increases the cost of the workload when using S3.

For applications that are handling large numbers of small files, it can be more cost effective to use Amazon EFS and mount the file system to the Lambda function. EFS charges based upon data storage and throughput, instead of number of files. To learn more about using EFS with Lambda, read this Compute Blog post.

Calculating the cost of the worker Lambda function

While parallelizing Lambda functions significantly reduces the overall processing time in this case, it’s also important to calculate the cost. To process the 3-hour video example in part 1, the function uses 345 invocations with 4096 MB of memory. Each invocation has an average duration of 4,311 ms.

Using the AWS Pricing Calculator, and ignoring the AWS Free Tier allowance, the costs to process this video is approximately $0.10.

AWS Pricing Calculator configuration

There are additional charges for other services used in the example application, such as EventBridge and S3. However, in terms of compute cost, this may compare favorably with server-based alternatives that you may have to scale manually depending on traffic. The exact cost depends upon your implementation and latency needs.

Deciding if a workload can be parallelized

The GIF generation workload is a good candidate for parallelization. This is because each 30-second block of work is independent and there is no strict ordering requirement. The end result is not impacted by the order that the GIFs are generated in. Each GIF also takes several seconds to generate, which is why the time saving comparison with the sequential, server-based approach is so significant.

Not all workloads can be parallelized and in many cases the work duration may be much shorter. This workload interacts with S3, which can scale to any level of read or write traffic created by the worker functions. You may use other downstream services that cannot scale this way, which may limit the amount of parallel processing you can use.

To learn more about designing and operating Lambda-based applications, read the Lambda Operator Guide.

Conclusion

Part 2 of this blog post expands on some of the advanced topics around scaling Lambda in parallelized workloads. It explains how the asynchronous invocation mode of Lambda scales and different ways to scale the worker Lambda function.

I cover how the example application manages memory, files, and temporary storage space. I also explain how to calculate the compute cost of using this approach, and considering if you can use parallelization in a workload.

For more serverless learning resources, visit Serverless Land.

Cloudflare Workers: the Fast Serverless Platform

Post Syndicated from Rita Kozlov original https://blog.cloudflare.com/cloudflare-workers-the-fast-serverless-platform/

Cloudflare Workers: the Fast Serverless Platform

Cloudflare Workers: the Fast Serverless Platform

Just about four years ago, we announced Cloudflare Workers, a serverless platform that runs directly on the edge.

Throughout this week, we will talk about the many ways Cloudflare is helping make applications that already exist on the web faster. But if today is the day you decide to make your idea come to life, building your project on the Cloudflare edge, and deploying it directly to the tubes of the Internet is the best way to guarantee your application will always be fast, for every user, regardless of their location.

It’s been a few years since we talked about how Cloudflare Workers compares to other serverless platforms when it comes to performance, so we decided it was time for an update. While most of our work on the Workers platform over the past few years has gone into making the platform more powerful: introducing new features, APIs, storage, debugging and observability tools, performance has not been neglected.

Today, Workers is 30% faster than it was three years ago at P90. And it is 210% faster than Lambda@Edge, and 298% faster than Lambda.

Oh, and also, we eliminated cold starts.

How do you measure the performance of serverless platforms?

I’ve run hundreds of performance benchmarks between CDNs in the past — the formula is simple: we use a tool called Catchpoint, which makes requests from nodes all over the world to the same asset, and reports back on the time it took for each location to return a response.

Measuring serverless performance is a bit different — since the thing you’re comparing is the performance of compute, rather than a static asset, we wanted to make sure all functions performed the same operation.

In our 2018 blog on speed testing, we had each function simply return the current time. For the purposes of this test, “serverless” products that were not able to meet the minimum criteria of being able to perform this task were disqualified. Serverless products used in this round of testing executed the same function, of identical computational complexity, to ensure accurate and fair results.

It’s also important to note what it is that we’re measuring. The reason performance matters, is because it impacts the experience of actual end customers. It doesn’t matter what the source of latency is: DNS, network congestion, cold starts… the customer doesn’t care what the source is, they care about wasting time waiting for their application to load.

It is therefore important to measure performance in terms of the end user experience — end to end, which is why we use global benchmarks to measure performance.

The result below shows tests run from 50 nodes all over the world, across North America, South America, Europe, Asia and Oceania.

Blue: Cloudflare Workers
Red: Lambda@Edge
Green: Lambda

(Link to results).

Cloudflare Workers: the Fast Serverless Platform

As you can see from the results, no matter where users are in the world, when it comes to speed, Workers can guarantee the best experience for customers.

In the case of Workers, getting the best performance globally requires no additional effort on the developers’ part. Developers do not need to do any additional load balancing, or configuration of regions. Every deployment is instantly live on Cloudflare’s extensive edge network.

Even if you’re not seeking to address a global audience, and your customer base is conveniently located on the East coast of the United States, Workers is able to guarantee the fastest response on all requests.

Cloudflare Workers: the Fast Serverless Platform

Above, we have the results just from Washington, DC, as close as we could get to us-east-1. And again, without any optimization, Workers is 34% faster.

Why is that?

What defines the performance of a serverless platform?

Other than the performance of the code itself, from the perspective of the end user, serverless application performance is fundamentally a function of two variables: distance an application executes from the user, and the time it takes the runtime itself to spin up. The realization that distance from the user is becoming a greater and greater bottleneck on application performance is causing many serverless vendors to push deeper and deeper into the edge. Running applications on the edge — closer to the end user — increases performance. As 5G comes online, this trend will only continue to accelerate.

However, many cloud vendors in the serverless space run into a critical problem when addressing the issue when competing for faster performance. And that is: the legacy architecture they’re using to build out their offerings doesn’t work well with the inherent limitations of the edge.

Since the goal behind the serverless model is to intentionally abstract away the underlying architecture, not everyone is clear on how legacy cloud providers like AWS have created serverless offerings like Lambda. Legacy cloud providers deliver serverless offerings by spinning up a containerized process for your code. The provider auto-scales all the different processes in the background. Every time a container is spun up, the entire language runtime is spun up with it, not just your code.

To help address the first graph, measuring global performance, vendors are attempting to move away from their large, centralized architecture (a few, big data centers) to a distributed, edge-based world (a greater number of smaller data centers all over the world) to close the distance between applications and end users. But there’s a problem with their approach: smaller data centers mean fewer machines, and less memory. Each time vendors pursue a small but many data centers strategy to operate closer to the edge, the likelihood of a cold start occurring on any individual process goes up.

This effectively creates a performance ceiling for serverless applications on container-based architectures. If legacy vendors with small data centers move your application closer to the edge (and the users), there will be fewer servers, less memory, and more likely that an application will need a cold start. To reduce the likelihood of that, they’re back to a more centralized model; but that means running your applications from one of a few big centralized data centers. These larger centralized data centers, by definition, are almost always going to be further away from your users.

You can see this at play in the graph above by looking at the results of the tests when running in Lambda@Edge — despite the reduced proximity to the end user, p90 performance is slower than that of Lambda’s, as containers have to spin up more frequently.

Serverless architectures built on containers can move up and down the frontier, but ultimately, there’s not much they can do to shift that frontier curve.

What makes Workers so fast?

Workers was designed from the ground up for an edge-first serverless model. Since Cloudflare started with a distributed edge network, rather than trying to push compute from large centralized data centers out into the edge, working under those constraints forced us to innovate.

In one of our previous blog posts, we’ve discussed how this innovation translated to a new paradigm shift with Workers’ architecture being built on lightweight V8 isolates that can spin up quickly, without introducing a cold start on every request.

Not only has running isolates given us advantage out of the box, but as V8 gets better, so does our platform. For example, when V8 announced Liftoff, a compiler for WASM, all WASM Workers instantly got faster.

Similarly, whenever improvements are made to Cloudflare’s network (for example, when we add new data centers) or stack (e.g., supporting new, faster protocols like HTTP/3), Workers instantly benefits from it.

Additionally, we’re always seeking to make improvements to Workers itself to make the platform even faster. For example, last year, we released an improvement that helped eliminate cold starts for our customers.

One key advantage that helps Workers identify and address performance gaps is the scale at which it operates. Today, Workers services hundreds of thousands of developers, ranging from hobbyists to enterprises all over the world, serving millions of requests per second. Whenever we make improvements for a single customer, the entire platform gets faster.

Performance that matters

The ultimate goal of the serverless model is to enable developers to focus on what they do best — build experiences for their users. Choosing a serverless platform that can offer the best performance out of the box means one less thing developers have to worry about. If you’re spending your time optimizing for cold starts, you’re not spending your time building the best feature for your customers.

Just like developers want to create the best experience for their users by improving the performance of their application, we’re constantly striving to improve the experience for developers building on Workers as well.

In the same way customers don’t want to wait for slow responses, developers don’t want to wait on slow deployment cycles.

This is where the Workers platform excels yet again.

Any deployment on Cloudflare Workers takes less than a second to propagate globally, so you don’t want to spend time waiting on your code deploy, and users can see changes as quickly as possible.

Of course, it’s not just the deployment time itself that’s important, but the efficiency of the full development cycle, which is why we’re always seeking to improve it at every step: from sign up to debugging.

Don’t just take our word for it!

Needless to say, much as we try to remain neutral, we’re always going to be just a little biased. Luckily, you don’t have to take our word for it.

We invite you to sign up and deploy your first Worker today — it’ll just take a few minutes!

Native Rust support on Cloudflare Workers

Post Syndicated from Steve Manuel original https://blog.cloudflare.com/workers-rust-sdk/

Native Rust support on Cloudflare Workers

Native Rust support on Cloudflare Workers

You can now write Cloudflare Workers in 100% Rust, no JavaScript required. Try it out: https://github.com/cloudflare/workers-rs

Cloudflare Workers has long supported the building blocks to run many languages using  WebAssembly. However, there has always been a challenging “trampoline” step required to allow languages like Rust to talk to JavaScript APIs such as fetch().

In addition to the sizable amount of boilerplate needed, lots of “off the shelf” bindings between languages don’t include support for Cloudflare APIs such as KV and Durable Objects. What we wanted was a way to write a Worker in idiomatic Rust, quickly, and without needing knowledge of the host JavaScript environment. While we had a nice “starter” template that made it easy enough to pull in some Rust libraries and use them from JavaScript, the barrier was still too high if your goal was to write a full program in Rust and ship it to our edge.

Not anymore!

Introducing the worker crate, available on GitHub and crates.io, which makes Rust developers feel right at home on the Workers platform by running code inside the V8 WebAssembly engine. In the snippet below, you can see how the worker crate does all the heavy lifting by providing Rustacean-friendly Workers APIs.

use worker::*;

#[event(fetch)]
pub async fn main(req: Request, env: Env) -> Result<Response> {
    console_log!(
        "{} {}, located at: {:?}, within: {}",
        req.method().to_string(),
        req.path(),
        req.cf().coordinates().unwrap_or_default(),
        req.cf().region().unwrap_or("unknown region".into())
    );

    if !matches!(req.method(), Method::Post) {
        return Response::error("Method Not Allowed", 405);
    }

    if let Some(file) = req.form_data().await?.get("file") {
        return match file {
            FormEntry::File(buf) => {
                Response::ok(&format!("size = {}", buf.bytes().await?.len()))
            }
            _ => Response::error("`file` part of POST form must be a file", 400),
        };
    }

    Response::error("Bad Request", 400)
}

Get your own Worker in Rust started with a single command:

# see installation instructions for our `wrangler` CLI at https://github.com/cloudflare/wrangler
# (requires v1.19.2 or higher)
$ wrangler generate --type=rust my-project

We’ve  stripped away all the glue code, provided an ergonomic HTTP framework, and baked in what you need to build small scripts or full-fledged Workers apps in Rust. You’ll find fetch, a router, easy-to-use HTTP functionality, Workers KV stores and Durable Objects, secrets, and environment variables too. It’s all open source, and we’d love your feedback!

Why are we doing this?

Cloudflare Workers is on a mission to simplify the developer experience. When we took a hard look at the previous experience writing non-JavaScript Workers, we knew we could do better. Rust happens to be a great language for us to kick-start our mission: it has first-class support for WebAssembly, and a wonderful, growing ecosystem. Tools like wasm-bindgen, libraries like web-sys, and Rust’s powerful macro system gave us a significant starting-off point. Plus, Rust’s popularity is growing rapidly, and if our own use of Rust at Cloudflare is any indication, there is no question that Rust is staking its claim as a must-have in the developer toolbox.

So give it a try, leave some feedback, even open a PR! By the way, we’re always on the lookout for great people to join us, and we are hiring for many open roles (including Rust engineers!) — take a look.

Building well-architected serverless applications: Optimizing application costs

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/building-well-architected-serverless-applications-optimizing-application-costs/

This series of blog posts uses the AWS Well-Architected Tool with the Serverless Lens to help customers build and operate applications using best practices. In each post, I address the serverless-specific questions identified by the Serverless Lens along with the recommended best practices. See the introduction post for a table of contents and explanation of the example application.

COST 1. How do you optimize your serverless application costs?

Design, implement, and optimize your application to maximize value. Asynchronous design patterns and performance practices ensure efficient resource use and directly impact the value per business transaction. By optimizing your serverless application performance and its code patterns, you can directly impact the value it provides, while making more efficient use of resources.

Serverless architectures are easier to manage in terms of correct resource allocation compared to traditional architectures. Due to its pay-per-value pricing model and scale based on demand, a serverless approach effectively reduces the capacity planning effort. As covered in the operational excellence and performance pillars, optimizing your serverless application has a direct impact on the value it produces and its cost. For general serverless optimization guidance, see the AWS re:Invent talks, “Optimizing your Serverless applications” Part 1 and Part 2, and “Serverless architectural patterns and best practices”.

Required practice: Minimize external calls and function code initialization

AWS Lambda functions may call other managed services and third-party APIs. Functions may also use application dependencies that may not be suitable for ephemeral environments. Understanding and controlling what your function accesses while it runs can have a direct impact on value provided per invocation.

Review code initialization

I explain the Lambda initialization process with cold and warm starts in “Optimizing application performance – part 1”. Lambda reports the time it takes to initialize application code in Amazon CloudWatch Logs. As Lambda functions are billed by request and duration, you can use this to track costs and performance. Consider reviewing your application code and its dependencies to improve the overall execution time to maximize value.

You can take advantage of Lambda execution environment reuse to make external calls to resources and use the results for subsequent invocations. Use TTL mechanisms inside your function handler code. This ensures that you can prevent additional external calls that incur additional execution time, while preemptively fetching data that isn’t stale.

Review third-party application deployments and permissions

When using Lambda layers or applications provisioned by AWS Serverless Application Repository, be sure to understand any associated charges that these may incur. When deploying functions packaged as container images, understand the charges for storing images in Amazon Elastic Container Registry (ECR).

Ensure that your Lambda function only has access to what its application code needs. Regularly review that your function has a predicted usage pattern so you can factor in the cost of other services, such as Amazon S3 and Amazon DynamoDB.

Required practice: Optimize logging output and its retention

Considering reviewing your application logging level. Ensure that logging output and log retention are appropriately set to your operational needs to prevent unnecessary logging and data retention. This helps you have the minimum of log retention to investigate operational and performance inquiries when necessary.

Emit and capture only what is necessary to understand and operate your component as intended.

With Lambda, any standard output statements are sent to CloudWatch Logs. Capture and emit business and operational events that are necessary to help you understand your function, its integration, and its interactions. Use a logging framework and environment variables to dynamically set a logging level. When applicable, sample debugging logs for a percentage of invocations.

In the serverless airline example used in this series, the booking service Lambda functions use Lambda Powertools as a logging framework with output structured as JSON.

Lambda Powertools is added to the Lambda functions as a shared Lambda layer in the AWS Serverless Application Model (AWS SAM) template. The layer ARN is stored in Systems Manager Parameter Store.

Parameters:
  SharedLibsLayer:
    Type: AWS::SSM::Parameter::Value<String>
    Description: Project shared libraries Lambda Layer ARN
Resources:
    ConfirmBooking:
        Type: AWS::Serverless::Function
        Properties:
            FunctionName: !Sub ServerlessAirline-ConfirmBooking-${Stage}
            Handler: confirm.lambda_handler
            CodeUri: src/confirm-booking
            Layers:
                - !Ref SharedLibsLayer
            Runtime: python3.7
…

The LOG_LEVEL and other Powertools settings are configured in the Globals section as Lambda environment variable for all functions.

Globals:
    Function:
        Environment:
            Variables:
                POWERTOOLS_SERVICE_NAME: booking
                POWERTOOLS_METRICS_NAMESPACE: ServerlessAirline
                LOG_LEVEL: INFO 

For Amazon API Gateway, there are two types of logging in CloudWatch: execution logging and access logging. Execution logs contain information that you can use to identify and troubleshoot API errors. API Gateway manages the CloudWatch Logs, creating the log groups and log streams. Access logs contain details about who accessed your API and how they accessed it. You can create your own log group or choose an existing log group that could be managed by API Gateway.

Enable access logs, and selectively review the output format and request fields that might be necessary. For more information, see “Setting up CloudWatch logging for a REST API in API Gateway”.

API Gateway logging

API Gateway logging

Enable AWS AppSync logging which uses CloudWatch to monitor and debug requests. You can configure two types of logging: request-level and field-level. For more information, see “Monitoring and Logging”.

AWS AppSync logging

AWS AppSync logging

Define and set a log retention strategy

Define a log retention strategy to satisfy your operational and business needs. Set log expiration for each CloudWatch log group as they are kept indefinitely by default.

For example, in the booking service AWS SAM template, log groups are explicitly created for each Lambda function with a parameter specifying the retention period.

Parameters:
    LogRetentionInDays:
        Type: Number
        Default: 14
        Description: CloudWatch Logs retention period
Resources:
    ConfirmBookingLogGroup:
        Type: AWS::Logs::LogGroup
        Properties:
            LogGroupName: !Sub "/aws/lambda/${ConfirmBooking}"
            RetentionInDays: !Ref LogRetentionInDays

The Serverless Application Repository application, auto-set-log-group-retention can update the retention policy for new and existing CloudWatch log groups to the specified number of days.

For log archival, you can export CloudWatch Logs to S3 and store them in Amazon S3 Glacier for more cost-effective retention. You can use CloudWatch Log subscriptions for custom processing, analysis, or loading to other systems. Lambda extensions allows you to process, filter, and route logs directly from Lambda to a destination of your choice.

Good practice: Optimize function configuration to reduce cost

Benchmark your function using a different set of memory size

For Lambda functions, memory is the capacity unit for controlling the performance and cost of a function. You can configure the amount of memory allocated to a Lambda function, between 128 MB and 10,240 MB. The amount of memory also determines the amount of virtual CPU available to a function. Benchmark your AWS Lambda functions with differing amounts of memory allocated. Adding more memory and proportional CPU may lower the duration and reduce the cost of each invocation.

In “Optimizing application performance – part 2”, I cover using AWS Lambda Power Tuning to automate the memory testing process to balances performance and cost.

Best practice: Use cost-aware usage patterns in code

Reduce the time your function runs by reducing job-polling or task coordination. This avoids overpaying for unnecessary compute time.

Decide whether your application can fit an asynchronous pattern

Avoid scenarios where your Lambda functions wait for external activities to complete. I explain the difference between synchronous and asynchronous processing in “Optimizing application performance – part 1”. You can use asynchronous processing to aggregate queues, streams, or events for more efficient processing time per invocation. This reduces wait times and latency from requesting apps and functions.

Long polling or waiting increases the costs of Lambda functions and also reduces overall account concurrency. This can impact the ability of other functions to run.

Consider using other services such as AWS Step Functions to help reduce code and coordinate asynchronous workloads. You can build workflows using state machines with long-polling, and failure handling. Step Functions also supports direct service integrations, such as DynamoDB, without having to use Lambda functions.

In the serverless airline example used in this series, Step Functions is used to orchestrate the Booking microservice. The ProcessBooking state machine handles all the necessary steps to create bookings, including payment.

Booking service state machine

Booking service state machine

To reduce costs and improves performance with CloudWatch, create custom metrics asynchronously. You can use the Embedded Metrics Format to write logs, rather than the PutMetricsData API call. I cover using the embedded metrics format in “Understanding application health” – part 1 and part 2.

For example, once a booking is made, the logs are visible in the CloudWatch console. You can select a log stream and find the custom metric as part of the structured log entry.

Custom metric structured log entry

Custom metric structured log entry

CloudWatch automatically creates metrics from these structured logs. You can create graphs and alarms based on them. For example, here is a graph based on a BookingSuccessful custom metric.

CloudWatch metrics custom graph

CloudWatch metrics custom graph

Consider asynchronous invocations and review run away functions where applicable

Take advantage of Lambda’s event-based model. Lambda functions can be triggered based on events ingested into Amazon Simple Queue Service (SQS) queues, S3 buckets, and Amazon Kinesis Data Streams. AWS manages the polling infrastructure on your behalf with no additional cost. Avoid code that polls for third-party software as a service (SaaS) providers. Rather use Amazon EventBridge to integrate with SaaS instead when possible.

Carefully consider and review recursion, and establish timeouts to prevent run away functions.

Conclusion

Design, implement, and optimize your application to maximize value. Asynchronous design patterns and performance practices ensure efficient resource use and directly impact the value per business transaction. By optimizing your serverless application performance and its code patterns, you can reduce costs while making more efficient use of resources.

In this post, I cover minimizing external calls and function code initialization. I show how to optimize logging output with the embedded metrics format, and log retention. I recap optimizing function configuration to reduce cost and highlight the benefits of asynchronous event-driven patterns.

This post wraps up the series, building well-architected serverless applications, where I cover the AWS Well-Architected Tool with the Serverless Lens . See the introduction post for links to all the blog posts.

For more serverless learning resources, visit Serverless Land.


Building a serverless distributed application using a saga orchestration pattern

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/building-a-serverless-distributed-application-using-a-saga-orchestration-pattern/

This post is written by Anitha Deenadayalan, Developer Specialist SA, DevAx (Developer Acceleration).

This post shows how to use the saga design pattern to preserve data integrity in distributed transactions across multiple services. In a distributed transaction, multiple services can be called before a transaction is completed. When the services store data in different data stores, it can be challenging to maintain data consistency across these data stores.

To maintain consistency in a transaction, relational databases provide two-phase commit (2PC). This consists of a prepare phase and a commit phase. In the prepare phase, the coordinating process requests the transaction’s participating processes (participants) to promise to commit or rollback the transaction. In the commit phase, the coordinating process requests the participants to commit the transaction. If the participants cannot agree to commit in the prepare phase, then the transaction is rolled back.

In distributed systems architected with microservices, two-phase commit is not an option as the transaction is distributed across various databases. In this case, one solution is to use the saga pattern.

A saga consists of a sequence of local transactions. Each local transaction in saga updates the database and triggers the next local transaction. If a transaction fails, then the saga runs compensating transactions to revert the database changes made by the preceding transactions.

There are two types of implementations for the saga pattern: choreography and orchestration.

Saga choreography

The saga choreography pattern depends on the events emitted by the microservices. The saga participants (microservices) subscribe to the events and they act based on the event triggers. For example, the order service in the following diagram emits an OrderPlaced event. The inventory service subscribes to that event and updates the inventory when the OrderPlaced event is emitted. Similarly the participant services act based on the context of the emitted event.

Solution architecture

Saga orchestration

The saga orchestration pattern has a central coordinator called orchestrator. The saga orchestrator manages and coordinates the entire transaction lifecycle. It is aware of the series of steps to be performed to complete the transaction. To run a step, it sends a message to the participant microservice to perform the operation. The participant microservice completes the operation and sends a message to the orchestrator. Based on the received message, the orchestrator decides which microservice to run next in the transaction:

Sage orchestrator in flow

You can use AWS Step Functions to implement the saga orchestration when the transaction is distributed across multiple databases.

Overview

This example uses a Step Functions workflow to implement the saga orchestration pattern, using the following architecture:

API Gateway to Lambda to Step Functions

When a customer calls the API, the invocation occurs, and pre-processing occurs in the Lambda function. The function starts the Step Functions workflow to start processing the distributed transaction.

The Step Functions workflow calls the individual services for order placement, inventory update, and payment processing to complete the transaction. It sends an event notification for further processing. The Step Functions workflow acts as the orchestrator to coordinate the transactions. If there is any error in the workflow, the orchestrator runs the compensatory transactions to ensure that the data integrity is maintained across various services.

When pre-processing is not required, you can also trigger the Step Functions workflow directly from API Gateway without the Lambda function.

The Step Functions workflow

The following diagram shows the steps that are run inside the Step Functions workflow. The green boxes show the steps that are run successfully. The order is placed, inventory is updated, and payment is processed before a Success state is returned to the caller.

The orange boxes indicate the compensatory transactions that are run when any one of the steps in the workflow fails. If the workflow fails at the Update inventory step, then the orchestrator calls the Revert inventory and Remove order steps before returning a Fail state to the caller. These compensatory transactions ensure that the data integrity is maintained. The inventory reverts to original levels and the order is reverted back.

Step Functions workflow

This preceding workflow is an example of a distributed transaction. The transaction data is stored across different databases and each service writes to its own database.

Prerequisites

For this walkthrough, you need:

Setting up the environment

For this walkthrough, use the AWS CDK code in the GitHub Repository to create the AWS resources. These include IAM roles, REST API using API Gateway, DynamoDB tables, the Step Functions workflow and Lambda functions.

  1. You need an AWS access key ID and secret access key for configuring the AWS Command Line Interface (AWS CLI). To learn more about configuring the AWS CLI, follow these instructions.
  2. Clone the repo:
    git clone https://github.com/aws-samples/saga-orchestration-netcore-blog
  3. After cloning, this is the directory structure:
    Directory structure
  4. The Lambda functions in the saga-orchestration directory must be packaged and copied to the cdk-saga-orchestration\lambdas directory before deployment. Run these commands to process the PlaceOrderLambda function:
    cd PlaceOrderLambda/src/PlaceOrderLambda 
    dotnet lambda package
    cp bin/Release/netcoreapp3.1/PlaceOrderLambda.zip ../../../../cdk-saga-orchestration/lambdas
    
  5. Repeat the same commands for all the Lambda functions in the saga-orchestration directory.
  6. Build the CDK code before deploying to the console:
    cd cdk-saga-orchestration/src/CdkSagaOrchestration
    dotnet build
    
  7. Install the aws-cdk package:
    npm install -g aws-cdk 
  8. The cdk synth command causes the resources defined in the application to be translated into an AWS CloudFormation template. The cdk deploy command deploys the stacks into your AWS account. Run:
    cd cdk-saga-orchestration
    cdk synth 
    cdk deploy
    
  9. CDK deploys the environment to AWS. You can monitor the progress using the CloudFormation console. The stack name is CdkSagaOrchestrationStack:
    CloudFormation console

The Step Functions configuration

The CDK creates the Step Functions workflow, DistributedTransactionOrchestrator. The following snippet defines the workflow with AWS CDK for .NET:

var stepDefinition = placeOrderTask
    .Next(new Choice(this, "Is order placed")
        .When(Condition.StringEquals("$.Status", "ORDER_PLACED"), updateInventoryTask
            .Next(new Choice(this, "Is inventory updated")
                .When(Condition.StringEquals("$.Status", "INVENTORY_UPDATED"),
                    makePaymentTask.Next(new Choice(this, "Is payment success")
                        .When(Condition.StringEquals("$.Status", "PAYMENT_COMPLETED"), successState)
                        .When(Condition.StringEquals("$.Status", "ERROR"), revertPaymentTask)))
                .When(Condition.StringEquals("$.Status", "ERROR"), waitState)))
        .When(Condition.StringEquals("$.Status", "ERROR"), failState));

Step Functions workflow

Compare the states language definition for the state machine with the definition above. Also observe the inputs and outputs for each step and how the conditions have been configured. The steps with type Task call a Lambda function for the processing. The steps with type Choice are decision-making steps that define the workflow.

Setting up the DynamoDB table

The Orders and Inventory DynamoDB tables are created using AWS CDK. The following snippet creates a DynamoDB table with AWS CDK for .NET:

var inventoryTable = new Table(this, "Inventory", new TableProps
{
    TableName = "Inventory",
    PartitionKey = new Attribute
    {
        Name = "ItemId",
        Type = AttributeType.STRING
    },
    RemovalPolicy = RemovalPolicy.DESTROY
});
  1. Open the DynamoDB console and select the Inventory table.
  2. Choose Create Item.
  3. Select Text, paste the following contents, then choose Save.
    {
      "ItemId": "ITEM001",
      "ItemName": "Soap",
      "ItemsInStock": 1000,
      "ItemStatus": ""
    }
    

    Create Item dialog

  4. Create two more items in the Inventory table:
    {
      "ItemId": "ITEM002",
      "ItemName": "Shampoo",
      "ItemsInStock": 500,
      "ItemStatus": ""
    }
    
    {
      "ItemId": "ITEM003",
      "ItemName": "Toothpaste",
      "ItemsInStock": 2000,
      "ItemStatus": ""
    }
    

The Lambda functions UpdateInventoryLambda and RevertInventoryLambda increment and decrement the ItemsInStock attribute value. The Lambda functions PlaceOrderLambda and UpdateOrderLambda insert and delete items in the Orders table. These are invoked by the saga orchestration workflow.

Triggering the saga orchestration workflow

The API Gateway endpoint, SagaOrchestratorAPI, is created using AWS CDK. To invoke the endpoint:

  1. From the API Gateway service page, select the SagaOrchestratorAPI:
    List of APIs
  2. Select Stages in the left menu panel:
    Stages menu
  3. Select the prod stage and copy the Invoke URL:
    Invoke URL
  4. From Postman, open a new tab. Select POST in the dropdown and enter the copied URL in the textbox. Move to the Headers tab and add a new header with the key ‘Content-Type’ and value as ‘application/json’:
    Postman configuration
  5. In the Body tab, enter the following input and choose Send.
    {
      "ItemId": "ITEM001",
      "CustomerId": "ABC/002",
      "MessageId": "",
      "FailAtStage": "None"
    }
    
  6. You see the output:
    Output
  7. Open the Step Functions console and view the execution. The graph inspector shows that the execution has completed successfully.
    Successful workflow execution
  8. Check the items in the DynamoDB tables, Orders & Inventory. You can see an item in the Orders table indicating that an order is placed. The ItemsInStock in the Inventory table has been deducted.
    Changes in DynamoDB tables
  9. To simulate the failure workflow in the saga orchestrator, send the following JSON as body in the Postman call. The FailAtStage parameter injects the failure in the workflow. Select Send in Postman after updating the Body:
    {
      "ItemId": "ITEM002",
      "CustomerId": "DEF/002",
      "MessageId": "",
      "FailAtStage": "UpdateInventory"
    }
    
  10. Open the Step Functions console to see the execution.
  11. While the function waits in the wait state, look at the items in the DynamoDB tables. A new item is added to the Orders table and the stock for Shampoo is deducted in the Inventory table.
    Changes in DynamoDB table
  12. Once the wait completes, the compensatory transaction steps are run:
    Workflow execution result
  13. In the graph inspector, select the Update Inventory step. On the right pane, click on the Step output tab. The status is ERROR, which changes the control flow to run the compensatory transactions.
    Step output
  14. Look at the items in the DynamoDB table again. The data is now back to a consistent state, as the compensatory transactions have run to preserve data integrity:
    DynamoDB table items

The Step Functions workflow implements the saga orchestration pattern. It performs the coordination across distributed services and runs the transactions. It also performs compensatory transactions to preserve the data integrity.

Cleaning up

To avoid incurring additional charges, clean up all the resources that have been created. Run the following command from a terminal window. This deletes all the resources that were created as part of this example.

cdk destroy

Conclusion

This post showed how to implement the saga orchestration pattern using API Gateway, Step Functions, Lambda, DynamoDB, and .NET Core 3.1. This can help maintain data integrity in distributed transactions across multiple services. Step Functions makes it easier to implement the orchestration in the saga pattern.

To learn more about developing microservices on AWS, refer to the whitepaper on microservices. To learn more about the features, refer to the AWS CDK Features page.

Building well-architected serverless applications: Optimizing application performance – part 3

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/building-well-architected-serverless-applications-optimizing-application-performance-part-3/

This series of blog posts uses the AWS Well-Architected Tool with the Serverless Lens to help customers build and operate applications using best practices. In each post, I address the serverless-specific questions identified by the Serverless Lens along with the recommended best practices. See the introduction post for a table of contents and explanation of the example application.

PERF 1. Optimizing your serverless application’s performance

This post continues part 2 of this security question. Previously, I look at designing your function to take advantage of concurrency via asynchronous and stream-based invocations. I cover measuring, evaluating, and selecting optimal capacity units.

Best practice: Integrate with managed services directly over functions when possible

Consider using native integrations between managed services as opposed to AWS Lambda functions when no custom logic or data transformation is required. This can enable optimal performance, requires less resources to manage, and increases security. There are also a number of AWS application integration services that enable communication between decoupled components with microservices.

Use native cloud services integration

When using Amazon API Gateway APIs, you can use the AWS integration type to connect to other AWS services natively. With this integration type, API Gateway uses Apache Velocity Template Language (VTL) and HTTPS to directly integrate with other AWS services.

Timeouts and errors must be managed by the API consumer. For more information on using VTL, see “Amazon API Gateway Apache Velocity Template Reference”. For an example application that uses API Gateway to read and write directly to/from Amazon DynamoDB, see “Building a serverless URL shortener app without AWS Lambda”.

API Gateway direct service integration

API Gateway direct service integration

There is also a tutorial available, Build an API Gateway REST API with AWS integration.

When using AWS AppSync, you can use VTL, direct integration with Amazon Aurora, Amazon Elasticsearch Service, and any publicly available HTTP endpoint. AWS AppSync can use multiple integration types and can maximize throughput at the data field level. For example, you can run full-text searches on the orderDescription field against Elasticsearch while fetching the remaining data from DynamoDB. For more information, see the AWS AppSync resolver tutorials.

In the serverless airline example used in this series, the catalog service uses AWS AppSync to provide a GraphQL API for searching flights. AWS AppSync uses DynamoDB as a database, and all compute logic is contained in the Apache Velocity Template (VTL).

Serverless airline catalog service using VTL

Serverless airline catalog service using VTL

AWS Step Functions integrates with multiple AWS services using service Integrations. For example, this allows you to fetch and put data into DynamoDB, or run an AWS Batch job. You can also publish messages to Amazon Simple Notification Service (SNS) topics, and send messages to Amazon Simple Queue Service (SQS) queues. For more details on the available integrations, see “Using AWS Step Functions with other services”.

Using Amazon EventBridge, you can connect your applications with data from a variety of sources. You can connect to various AWS services natively, and act as an event bus across multiple AWS accounts to ease integration. You can also use the API destination feature to route events to services outside of AWS. EventBridge handles the authentication, retries, and throughput. For more details on available EventBridge targets, see the documentation.

Amazon EventBridge

Amazon EventBridge

Good practice: Optimize access patterns and apply caching where applicable

Consider caching when clients may not require up to date data. Optimize access patterns to only fetch data that is necessary to end users. This improves the overall responsiveness of your workload and makes more efficient use of compute and data resources across components.

Implement caching for suitable access patterns

For REST APIs, you can use API Gateway caching to reduce the number of calls made to your endpoint and also improve the latency of requests to your API. When you enable caching for a stage or method, API Gateway caches responses for a specified time-to-live (TTL) period. API Gateway then responds to the request by looking up the endpoint response from the cache, instead of making a request to your endpoint.

API Gateway caching

API Gateway caching

For more information, see “Enabling API caching to enhance responsiveness”.

For geographically distributed clients, Amazon CloudFront or your third-party CDN can cache results at the edge and further reducing network round-trip latency.

For GraphQL APIs, AWS AppSync provides built-in server-side caching at the API level. This reduces the need to access data sources directly by making data available in a high-speed in-memory cache. This improves performance and decreases latency. For queries with common arguments or a restricted set of arguments, you can also enable caching at the resolver level to improve overall responsiveness. For more information, see “Improving GraphQL API performance and consistency with AWS AppSync Caching”.

When using databases, cache results and only connect to and fetch data when needed. This reduces the load on the downstream database and improves performance. Include a caching expiration mechanism to prevent serving stale records. For more information on caching implementation patterns and considerations, see “Caching Best Practices”.

For DynamoDB, you can enable caching with Amazon DynamoDB Accelerator (DAX). DAX enables you to benefit from fast in-memory read performance in microseconds, rather than milliseconds. DAX is suitable for use cases that may not require strongly consistent reads. Some examples include real-time bidding, social gaming, and trading applications. For more information, read “Use cases for DAX“.

For general caching purposes, Amazon ElastiCache provides a distributed in-memory data store or cache environment. ElastiCache supports a variety of caching patterns through key-value stores using the Redis and Memcache engines. Define what is safe to cache, even when using popular caching patterns like lazy caching or write-through. Set a TTL and eviction policy that fits your baseline performance and access patterns. This ensures that you don’t serve stale records or cache data that should have a strongly consistent read. For more information on ElastiCache caching and time-to-live strategies, see the documentation.

For additional serverless caching suggestions, see the AWS Serverless Hero blog post “All you need to know about caching for serverless applications”.

Reduce overfetching and underfetching

Over-fetching is when a client downloads too much data from a database or endpoint. This results in data in the response that you don’t use. Under-fetching is not having enough data in the response. The client then needs to make additional requests to receive the data. Overfetching and underfetching can both affect performance.

To fetch a collection of items from a DynamoDB table, you can perform a query or a scan. A scan operation always scans the entire table or secondary index. It then filters out values to provide the result you want, essentially adding the extra step of removing data from the result set. A query operation finds items directly based on primary key values.

For faster response times, design your tables and indexes so that your applications can use query instead of scan. Use both Global Secondary Index (GSI) in addition to composite sort keys to help you query hierarchical relationships in your data. For more information, see “Best Practices for Querying and Scanning Data”.

Consider GraphQL and AWS AppSync for interactive web applications, mobile, real-time, or for use cases where data drives the user interface. AWS AppSync provides data fetching flexibility, which allows your client to query only for the data it needs, in the format it needs it. Ensure you do not make too many nested queries where a long response may result in timeouts. GraphQL helps you adapt access patterns as your workload evolves. This makes it more flexible as it allows you to move to purpose-built databases if necessary.

Compress payload and data storage

Some AWS services allow you to compress the payload or compress data storage. This can improve performance by sending and receiving less data, and can save on data storage, which can also reduce costs.

If your content supports deflate, gzip or identity content encoding, API Gateway allows your client to call your API with compressed payloads. By default, API Gateway supports decompression of the method request payload. However, you must configure your API to enable compression of the method response payload. Compression in API Gateway and decompression in the client might increase overall latency and require more computing times. Run test cases against your API to determine an optimal value. For more information, see “Enabling payload compression for an API”.

Amazon Kinesis Data Firehose supports compressing streaming data using gzip, snappy, or zip. This minimizes the amount of storage used at the destination. The Amazon Kinesis Data Firehose FAQs has more information on compression. Kinesis Data Firehose also supports converting your streaming data from JSON to Apache Parquet or Apache ORC before storing the data in Amazon S3. Parquet and ORC are columnar data formats that save space and enable faster queries compared to row-oriented formats like JSON.

Conclusion

Evaluate and optimize your serverless application’s performance based on access patterns, scaling mechanisms, and native integrations. You can improve your overall experience and make more efficient use of the platform in terms of both value and resources.

In part 1, I cover measuring and optimizing function startup time. I explain cold and warm starts and how to reuse the Lambda execution environment to improve performance. I explain how only importing necessary libraries and dependencies increases application performance.

In part 2, I look at designing your function to take advantage of concurrency via asynchronous and stream-based invocations. I cover measuring, evaluating, and selecting optimal capacity units.

In this post, I look at integrating with managed services directly over functions when possible. I cover optimizing access patterns and applying caching where applicable.

In the next post in the series, I cover the cost optimization pillar from the Well-Architected Serverless Lens.

For more serverless learning resources, visit Serverless Land.

Increasing performance of Java AWS Lambda functions using tiered compilation

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/increasing-performance-of-java-aws-lambda-functions-using-tiered-compilation/

This post is written by Mark Sailes, Specialist Solutions Architect, Serverless and Richard Davison, Senior Partner Solutions Architect.

The Operating Lambda: Performance optimization blog series covers important topics for developers, architects, and system administrators who are managing applications using AWS Lambda functions. This post explains how you can reduce the initialization time to start a new execution environment when using the Java-managed runtimes.

Lambda lifecycle

Many Lambda workloads are designed to deliver fast responses to synchronous or asynchronous workloads in a fraction of a second. Examples of these could be public APIs to deliver dynamic content to websites or a near-real time data pipeline doing small batch processing.

As usage of these systems increases, Lambda creates new execution environments. When a new environment is created and used for the first time, additional work is done to make it ready to process an event. This creates two different performance profiles: one with and one without the additional work.

To improve the response time, you can minimize the effect of this additional work. One way you can minimize the time taken to create a new managed Java execution environment is to tune the JVM. It can be optimized specifically for these workloads that do not have long execution durations.

One example of this is configuring a feature of the JVM called tiered compilation. From version 8 of the Java Development Kit (JDK), the two just-in-time compilers C1 and C2 have been used in combination. C1 is designed for use on the client side and to enable short feedback loops for developers. C2 is designed for use on the server side and to achieve higher performance after profiling.

Tiering is used to determine which compiler to use to achieve better performance. These are represented as five levels:

Tiering levels

Profiling has an overhead, and performance improvements are only achieved after a method has been invoked a number of times, the default being 10,000. Lambda customers wanting to achieve faster startup times can use level 1 with little risk of reducing warm start performance. The article “Startup, containers & Tiered Compilation” explains tiered compilation further.

For customers who are doing highly repetitive processing, this configuration might not be suited. Applications that repeat the same code paths many times want the JVM to profile and optimize these paths. Concrete examples of these would be using Lambda to run Monte Carlo simulation or hash calculations. You can run the same simulations thousands of times and the JVM profiling can reduce the total execution time significantly.

Performance improvements

The example project is a Java 11-based application used to analyze the impact of this change. The application is triggered by Amazon API Gateway and then puts an item into Amazon DynamoDB. To compare the performance difference caused by this change, there is one Lambda function with the additional changes and one without. There are no other differences in the code.

Download the code for this example project from the GitHub repo: https://github.com/aws-samples/aws-lambda-java-tiered-compilation-example.

To install prerequisite software:

  1. Install the AWS CDK.
  2. Install Apache Maven, or use your preferred IDE.
  3. Build and package the Java application in the software folder:
    cd software/ExampleFunction/
    mvn package
  4. Zip the execution wrapper script:
    cd ../OptimizationLayer/
    ./build-layer.sh
    cd ../../
  5. Synthesize CDK. This previews changes to your AWS account before it makes them:
    cd infrastructure
    cdk synth
  6. Deploy the Lambda functions:
    cdk deploy --outputs-file outputs.json

The API Gateway endpoint URL is displayed in the output and saved in a file named outputs.json. The contents are similar to:

InfrastructureStack.apiendpoint = https://{YOUR_UNIQUE_ID_HERE}.execute-api.eu-west-1.amazonaws.com

Using Artillery to load test the changes

First, install prerequisites:

  1. Install jq and Artillery Core.
  2. Run the following two scripts from the /infrastructure directory:
    artillery run -t $(cat outputs.json | jq -r '.InfrastructureStack.apiendpoint') -v '{ "url": "/without" }' loadtest.yml
    
    artillery run -t $(cat outputs.json | jq -r '.InfrastructureStack.apiendpoint') -v '{ "url": "/with" }' loadtest.yml

Check the results using Amazon CloudWatch Insights

  1. Navigate to Amazon CloudWatch.
  2. Select Logs then Logs Insights.
  3. Select the following two log groups from the drop-down list:
    /aws/lambda/example-with-layer
    /aws/lambda/example-without-layer
  4. Copy the following query and choose Run query:
        filter @type = "REPORT"
        | parse @log /\d+:\/aws\/lambda\/example-(?<function>\w+)-\w+/
        | stats
        count(*) as invocations,
        pct(@duration, 0) as p0,
        pct(@duration, 25) as p25,
        pct(@duration, 50) as p50,
        pct(@duration, 75) as p75,
        pct(@duration, 90) as p90,
        pct(@duration, 95) as p95,
        pct(@duration, 99) as p99,
        pct(@duration, 100) as p100
        group by function, ispresent(@initDuration) as coldstart
        | sort by function, coldstart
    

    Query window

You see results similar to:

Query results

Here is a simplified table of the results:

Settings Type

# of invocations

p90 (ms)

p95 (ms)

p99 (ms)

Default settings Cold start

754

5,212

5,338

5,517

Default settings Warm start

35,247

58

93

255

Tiered compilation stopping at level 1 Cold start

383

2,071

2,086

2,221

Tiered compilation stopping at level 1 Warm start

35,618

23

32

86

The results are from testing 120 concurrent requests over 5 minutes using an open-source software project called Artillery. You can find instructions on how to run these tests in the GitHub repo. The results show that for this application, cold starts for 90% of invocations improve by 3141 ms (60%). These numbers are specific for this application and your application may behave differently.

Using wrapper scripts for Lambda functions

Wrapper scripts are a feature available in Java 8 and Java 11 on Amazon Linux 2 managed runtimes. They are not available for the Java 8 on Amazon Linux 1 managed runtime.

To apply this optimization flag to Java Lambda functions, create a wrapper script and add it to a Lambda layer zip file. This script will alter the JVM flags which Java is started with, within the execution environment.

#!/bin/sh
shift
export _JAVA_OPTIONS="-XX:+TieredCompilation -XX:TieredStopAtLevel=1"
java "$@"

Read the documentation to learn how to create and share a Lambda layer.

Console walkthrough

This change can be configured using AWS Serverless Application Model (AWS SAM), the AWS Command Line Interface (AWS CLI), AWS CloudFormation, or from within the AWS Management Console.

Using the AWS Management Console:

  1. Navigate to the AWS Lambda console.
  2. Select Functions and choose the Lambda function to add the layer to.
    Lambda functions
  3. The Code tab is selected by default. Scroll down to the Layers panel.
  4. Select Add a layer.
    Add a layer
  5. Select Custom layers and choose your layer.
    Add layer
  6. Select the Version. Choose Add.
  7. From the menu, select the Configuration tab and Environment variables. Choose Edit.
    Configuration tab
  8. Choose Add environment variable. Add the following:
    – Key: AWS_LAMBDA_EXEC_WRAPPER
    – Value: /opt/java-exec-wrapper
    Edit environment variables
  9. Choose Save.You can verify that the changes are applied by invoking the function and viewing the log events. The log line Picked up _JAVA_OPTIONS: -XX:+TieredCompilation -XX:TieredStopAtLevel=1 is added.Log events

Conclusion

Tiered compilation stopping at level 1 reduces the time the JVM spends optimizing and profiling your code. This could help reduce start up times for Java applications that require fast responses, where the workload doesn’t meet the requirements to benefit from profiling.

You can make further reductions in startup time using GraalVM. Read more about GraalVM and the Quarkus framework in the architecture blog. View the code example at https://github.com/aws-samples/aws-lambda-java-tiered-compilation-example to see how you can apply this to your Lambda functions.
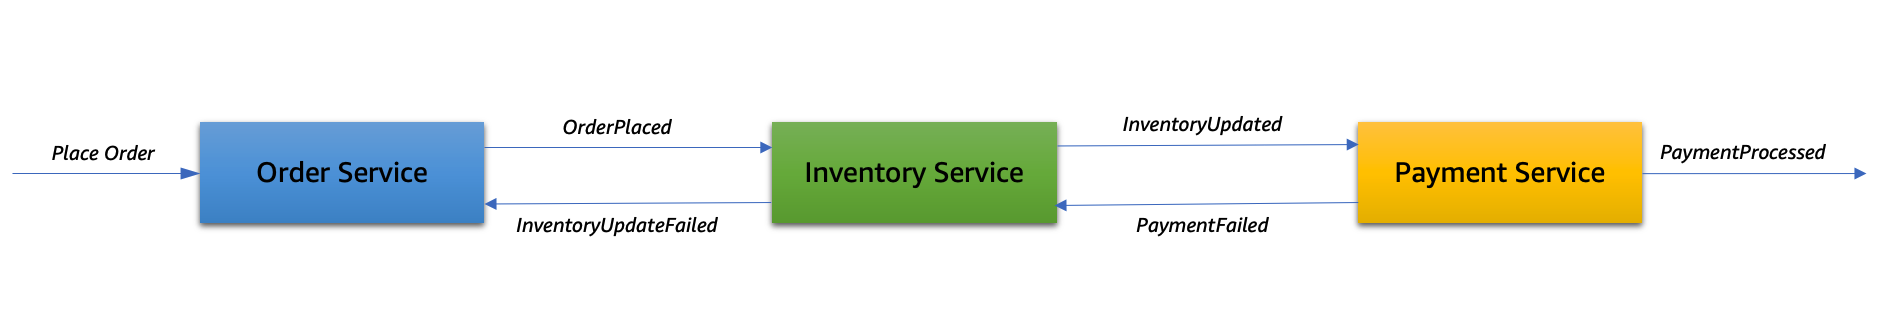
For more serverless learning resources, visit Serverless Land.

Building a serverless GIF generator with AWS Lambda: Part 1

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/building-a-serverless-gif-generator-with-aws-lambda-part-1/

Many video streaming services show GIF animations in the frontend when users fast forward and rewind throughout a video. This helps customers see a preview and makes the user interface more intuitive.

Generating these GIF files is a compute-intensive operation that becomes more challenging to scale when there are many videos. Over a typical 2-hour movie with GIF previews every 30 seconds, you need 240 separate GIF animations to support this functionality.

In a server-based solution, you can use a library like FFmpeg to load the underlying MP4 file and create the GIF exports. However, this may be a serial operation that slows down for longer videos or when there are many different videos to process. For a service providing thousands of videos to customers, they need a solution where the encoding process keeps pace with the number of videos.

In this two-part blog post, I show how you can use a serverless approach to create a scalable GIF generation service. I explain how you can use parallelization in AWS Lambda-based workloads to reduce processing time significantly.

The example application uses the AWS Serverless Application Model (AWS SAM), enabling you to deploy the application more easily in your own AWS account. This walkthrough creates some resources covered in the AWS Free Tier but others incur cost. To set up the example, visit the GitHub repo and follow the instructions in the README.md file.

Overview

To show the video player functionality, visit the demo front end. This loads the assets for an example video that is already processed. In the example, there are GIF animations every 30 seconds and freeze frames for every second of video. Move the slider to load the frame and GIF animation at that point in the video:

Serverless GIF generator demo

  1. The demo site defaults to an existing video. After deploying the backend application, you can test your own videos here.
  2. Move the slider to select a second in the video playback. This simulates a typical playback bar used in video application frontends.
  3. This displays the frame at the chosen second, which is a JPG file created by the backend application.
  4. The GIF animation for the selected playback point is a separate GIF file, created by the backend application.

Comparing server-based and serverless solutions

The example application uses FFmpeg, an open source application to record and process video. FFmpeg creates the GIF animations and individual frames for each second of video. You can use FFmpeg directly from a terminal or in scripts and applications. In comparing the performance, I use the AWS re:Invent 2019 keynote video, which is almost 3 hours long.

To show the server-based approach, I use a Node.js application in the GitHub repo. This loops through the video length in 30-second increments, calling FFmpeg with the necessary command line parameters:

const main = async () => {
	const length = 10323
	const inputVideo = 'test.mp4'
	const ffTmp = './output'
	const snippetSize = 30
 	const baseFilename = inputVideo.split('.')[0]

	console.time('task')
	for (let start = 0; start < length; start += snippetSize) {
		const gifName = `${baseFilename}-${start}.gif`
		const end = start + snippetSize -1

		console.log('Now creating: ', gifName)
		// Generates gif in local tmp
		await execPromise(`${ffmpegPath} -loglevel error -ss ${start} -to ${end} -y -i "${inputVideo}" -vf "fps=10,scale=240:-1:flags=lanczos,split[s0][s1];[s0]palettegen[p];[s1][p]paletteuse" -loop 0 ${ffTmp}/${gifName}`)
		await execPromise(`${ffmpegPath} -loglevel error -ss ${start} -to ${end} -i "${inputVideo}" -vf fps=1 ${ffTmp}/${baseFilename}-${start}-frame-%d.jpg`)
	}
	console.timeEnd('task')
}

Running this script from my local development machine, it takes almost 21 minutes to complete the operation and creates over 10,000 output files.

Script output

After deploying the example serverless application in the GitHub repo, I upload the video to the source Amazon S3 bucket using the AWS CLI:

aws s3 cp ./reinvent.mp4 s3://source-bucket-name --acl public-read

The completed S3 PutObject operation starts the GIF generation process. The function that processes the GIF files emits the following metrics on the Monitor tab in the Lambda console:

Lambda function metrics

  1. There are 345 invocations to process the source file into 30-second GIF animations.
  2. The average duration for each invocation is 4,311 ms. The longest is 9,021 ms.
  3. No errors occurred in processing the video.
  4. Lambda scaled up to 344 concurrent execution environments.

After approximately 10 seconds, the conversion is complete and there are over 10,000 objects in the application’s output S3 bucket:

Test results

The main reason that the task duration is reduced from nearly 21 minutes to around 10 seconds is parallelization. In the server-based approach, each 30 second GIF is processed sequentially. In the Lambda-based solution, all of the 30-second clips are generated in parallel, at around the same time:

Server-based vs Lambda-based

Solution architecture

The example application uses the following serverless architecture:

Solution architecture

  1. When the original MP4 video is put into the source S3 bucket, it invokes the first Lambda function.
  2. The Snippets Lambda function detects the length of the video. It determines the number of 30-second snippets and then puts events onto the default event bus. There is one event for each snippet.
  3. An Amazon EventBridge rule matches for events created by the first Lambda function. It invokes the second Lambda function.
  4. The Process MP4 Lambda function receives the event as a payload. It loads the original video using FFmpeg to generate the GIF and per-second frames.
  5. The resulting files are stored in the output S3 bucket.

The first Lambda function uses the following code to detect the length of the video and create events for EventBridge:

const createSnippets = async (record) => {
	// Get signed URL for source object
	const params = {
		Bucket: record.s3.bucket.name, 
		Key: record.s3.object.key, 
		Expires: 300
	}
	const url = s3.getSignedUrl('getObject', params)

	// Get length of source video
	const metadata = await ffProbe(url)
	const length = metadata.format.duration
	console.log('Length (seconds): ', length)

	// Build data array for DynamoDB
	const items = []
	const snippetSize = parseInt(process.env.SnippetSize)

	for (let start = 0; start < length; start += snippetSize) {
		items.push({
			key: record.s3.object.key,
			start,
			end: (start + snippetSize - 1),
			length,
			tsCreated: Date.now()
		})
	}
	// Send events to EventBridge
	await writeBatch(items)
}

The eventbridge.js file contains a function that sends the event array to the default bus in EventBridge. It uses the putEvents method in the EventBridge JavaScript SDK to send events in batches of 10:

const writeBatch = async (items) => {

    console.log('writeBatch items: ', items.length)

    for (let i = 0; i < items.length; i += BATCH_SIZE ) {
        const tempArray = items.slice(i, i + BATCH_SIZE)

        // Create new params array
        const paramsArray = tempArray.map((item) => {
            return {
                DetailType: 'newVideoCreated',
                Source: 'custom.gifGenerator',
                Detail: JSON.stringify ({
                    ...item
                })
            }
        })

        // Create params object for DDB DocClient
        const params = {
            Entries: paramsArray
        }

        // Write to DDB
        const result = await eventbridge.putEvents(params).promise()
        console.log('Result: ', result)
    }
}

The second Lambda function is invoked by an EventBridge rule, matching on the Source and DetailType values. Both the Lambda function and the rule are defined in the AWS SAM template:

  GifsFunction:
    Type: AWS::Serverless::Function 
    Properties:
      CodeUri: gifsFunction/
      Handler: app.handler
      Runtime: nodejs14.x
      Timeout: 30
      MemorySize: 4096
      Layers:
        - !Ref LayerARN
      Environment:
        Variables:
          GenerateFrames: !Ref GenerateFrames
          GifsBucketName: !Ref GifsBucketName
          SourceBucketName: !Ref SourceBucketName
      Policies:
        - S3ReadPolicy:
            BucketName: !Ref SourceBucketName
        - S3CrudPolicy:
            BucketName: !Ref GifsBucketName
      Events:
        Trigger:
          Type: EventBridgeRule 
          Properties:
            Pattern:        
              source:
                - custom.gifGenerator
              detail-type:
                - newVideoCreated        

This Lambda function receives an event payload specifying the start and end time for the video clip it should process. The function then calls the FFmpeg application to generate the output files. It stores these in the local /tmp storage before uploading to the output S3 bucket:

const processMP4 = async (event) => {
    // Get settings from the incoming event
    const originalMP4 = event.detail.Key 
    const start =  event.detail.start
    const end =  event.detail.end

    // Get signed URL for source object
    const params = {
        Bucket: process.env.SourceBucketName, 
        Key: originalMP4, 
        Expires
    }
    const url = s3.getSignedUrl('getObject', params)
    console.log('processMP4: ', { url, originalMP4, start, end })

    // Extract frames from MP4 (1 per second)
    console.log('Create GIF')
    const baseFilename = params.Key.split('.')[0]
    
    // Create GIF
    const gifName = `${baseFilename}-${start}.gif`
    // Generates gif in local tmp
    await execPromise(`${ffmpegPath} -loglevel error -ss ${start} -to ${end} -y -i "${url}" -vf "fps=10,scale=240:-1:flags=lanczos,split[s0][s1];[s0]palettegen[p];[s1][p]paletteuse" -loop 0 ${ffTmp}/${gifName}`)
    // Upload gif to local tmp
    // Generate frames
    if (process.env.GenerateFrames === 'true') {    
        console.log('Capturing frames')
        await execPromise(`${ffmpegPath} -loglevel error -ss ${start} -to ${end} -i "${url}" -vf fps=1 ${ffTmp}/${baseFilename}-${start}-frame-%d.jpg`)
    }

    // Upload all generated files
    await uploadFiles(`${baseFilename}/`)

    // Cleanup temp files
    await tmpCleanup()
}

Creating and using the FFmpeg Lambda layer

FFmpeg uses operating system-specific binaries that may be different on your development machine from the Lambda execution environment. The easiest way to test the code on a local machine and deploy to Lambda with the appropriate binaries is to use a Lambda layer.

As described in the example application’s README file, you can create the FFmpeg Lambda layer by deploying the ffmpeg-lambda-layer application in the AWS Serverless Application Repository. After deployment, the Layers menu in the Lambda console shows the new layer. Copy the version ARN and use this as a parameter in the AWS SAM deployment:

ffmpeg Lambda layer

On your local machine, download and install the FFmpeg binaries for your operating system. The package.json file for the Lambda functions uses two npm installer packages to help ensure the Node.js code uses the correct binaries when tested locally:

{
  "name": "gifs",
  "version": "1.0.0",
  "description": "",
  "main": "index.js",
  "scripts": {
    "test": "echo \"Error: no test specified\" && exit 1"
  },
  "keywords": [],
  "author": "James Beswick",
  "license": "MIT-0",
  "dependencies": {
  },
  "devDependencies": {
    "@ffmpeg-installer/ffmpeg": "^1.0.20",
    "@ffprobe-installer/ffprobe": "^1.1.0",
    "aws-sdk": "^2.927.0"
  }
}

Any npm packages specified in the devDependencies section of package.json are not deployed to Lambda by AWS SAM. As a result, local testing uses local ffmpeg binaries and Lambda uses the previously deployed Lambda layer. This approach also helps to reduce the size of deployment uploads and can help make the testing and deployment cycle faster in development.

Using FFmpeg from a Lambda function

FFmpeg is an application that’s generally used via a terminal. It takes command line parameters as options to determine input files, output locations, and the type of processing needed. To use terminal commands from Lambda, both functions use the asynchronous child_process module in Node.js. The execPromise function wraps this module in a Promise so the main function can use async/await syntax:

const { exec } = require('child_process')

const execPromise = async (command) => {
    console.log(command)
    return new Promise((resolve, reject) => {
        const ls = exec(command, function (error, stdout, stderr) {
          if (error) {
            console.error('Error: ', error)
            reject(error)
          }
          if (stdout) console.log('stdout: ', stdout)
          if (stderr) console.error('stderr: ' ,stderr)
        })
        
        ls.on('exit', (code) => {
          console.log('execPromise finished with code ', code)
          resolve()
        })
    })
}

As a result, you can then call FFmpeg by constructing a command line with options parameters and passing to execPromise:

await execPromise(`${ffmpegPath} -loglevel error -ss ${start} -to ${end} -i "${url}" -vf fps=1 ${ffTmp}/${baseFilename}-${start}-frame-%d.jpg`)

Alternatively, you can also use the fluent-ffmpeg npm library, which exposes the command line options as methods. The example application uses this in the ffmpeg-promisify.js file:

const ffmpeg = require("fluent-ffmpeg")
   ffmpeg(source)
      .noAudio()
      .size(`${IMG_WIDTH}x${IMG_HEIGHT}`)
      .setStartTime(startFormatted)
      .setDuration(snippetSize - 1)
      .output(outputFile)
      .on("end", async (err) => {
        // do work
      })
      .on("error", function (err) {
        console.error('FFMPEG error: ', err)
      })
      .run()

Deploying the application

In the GitHub repository, there are detailed deployment instructions for the example application. The repo contains separate directories for the demo frontend application, server-based script, and the two versions of backend service.

After deployment, you can test the application by uploading an MP4 video to the source S3 bucket. The output GIF and JPG files are written to the application’s destination S3 bucket. The files from each MP4 file are grouped in a folder in the bucket:

S3 bucket contents

Frontend application

The frontend application allows you to visualize the outputs of the backend application. There is also a hosted version of this application. This accepts custom parameters to load graphics resources from S3 buckets in your AWS account. Alternatively, you can run the frontend application locally.

To launch the frontend application:

  1. After cloning the repo, change to the frontend directory.
  2. Run npm install to install Vue.js and all the required npm modules from package.json.
  3. Run npm run serve to start the development server. After building the modules in the project, the terminal shows the local URL where the application is running:
    Terminal output
  4. Open a web browser and navigate to http://localhost:8080 to see the application:
    Localhost browser application

Conclusion

In part 1 of this blog post, I explain how a GIF generation service can support a front-end application for video streaming. I compare the performance of a server-based and serverless approach and show how parallelization can significantly improve processing time. I walk through the solution architecture used in the example application and show how you can use FFmpeg in Lambda functions.

Part 2 covers advanced topics around this implementation. It explains the scaling behavior and considers alternative approaches, and looks at the cost of using this service.

For more serverless learning resources, visit Serverless Land.

Toyota Connected and AWS Design and Deliver Collision Assistance Application

Post Syndicated from Srikanth Kodali original https://aws.amazon.com/blogs/architecture/toyota-connected-and-aws-design-and-deliver-collision-assistance-application/

This post was cowritten by Srikanth Kodali, Sr. IoT Data Architect at AWS, and Will Dombrowski, Sr. Data Engineer at Toyota Connected

Toyota Connected North America (TC) is a technology/big data company that partners with Toyota Motor Corporation and Toyota Motor North America to develop products that aim to improve the driving experience for Toyota and Lexus owners.

TC’s Mobility group provides backend cloud services that are built and hosted in AWS. Together, TC and AWS engineers designed, built, and delivered their new Collision Assistance product, which debuted in early August 2021.

In the aftermath of an accident, Collision Assistance offers Toyota and Lexus drivers instructions to help them navigate a post-collision situation. This includes documenting the accident, filing an insurance claim, and transitioning to the repair process.

In this blog post, we’ll talk about how our team designed, built, refined, and deployed the Collision Assistance product with Serverless on AWS services. We’ll discuss our goals in developing this product and the architecture we developed based on those goals. We’ll also present issues we encountered when testing our initial architecture and how we resolved them to create the final product.

Building a scalable, affordable, secure, and high performing product

We used a serverless architecture because it is often less complex than other architecture types. Our goals in developing this initial architecture were to achieve scalability, affordability, security, and high performance, as described in the following sections.

Scalability and affordability

In our initial architecture, Amazon Simple Queue Service (Amazon SQS) queues, Amazon Kinesis streams, and AWS Lambda functions allow data pipelines to run servers only when they’re needed, which introduces cost savings. They also process data in smaller units and run them in parallel, which allows data pipelines to scale up efficiently to handle peak traffic loads. These services allow for an architecture that can handle non-uniform traffic without needing additional application logic.

Security

Collision Assistance can deliver information to customers via push notifications. This data must be encrypted because many data points the application collects are sensitive, like geolocation.

To secure this data outside our private network, we use Amazon Simple Notification Service (Amazon SNS) as our delivery mechanism. Amazon SNS provides HTTPS endpoint delivery of messages coming to topics and subscriptions. AWS allows us to enable at-rest and/or in-transit encryption for all of our other architectural components as well.

Performance

To quantify our product’s performance, we review the “notification delay.” This metric evaluates the time between the initial collision and when the customer receives a push notification from Collision Assistance. Our ultimate goal is to have the push notification sent within minutes of a crash, so drivers have this information in near real time.

Initial architecture

Figure 1 presents our initial architecture implementation that aims to predict whether a crash has occurred and reduce false positives through the following data pipeline:

  1. The Kinesis stream receives vehicle data from an upstream ingestion service, as discussed in the Enhancing customer safety by leveraging the scalable, secure, and cost-optimized Toyota Connected Data Lake blog.
  2. A Lambda function writes lookup data to Amazon DynamoDB for every Kinesis record.
  3. This Lambda function decreases obvious non-crash data. It sends the current record (X) to Amazon SQS. If X exceeds a certain threshold, it will remain a crash candidate.
  4. Amazon SQS sets a delivery delay so that there will be more Kinesis/DynamoDB records available when X is processed later in the pipeline.
  5. A second Lambda function reads the data from the SQS message. It queries DynamoDB to find the Kinesis lookup data for the message before (X-1) and after (X+1) the crash candidate.
  6. Kinesis GetRecords retrieves X-1 and X+1, because X+1 will exist after the SQS delivery delay times out.
  7. The X-1, X, and X+1 messages are sent to the data science (DS) engine.
  8. When a crash is accurately predicted, these results are stored in a DynamoDB table.
  9. The push notification is sent to the vehicle owner. (Note: the push notification is still in ‘select testing phase’)
Diagram and description of our initial architecture implementation

Figure 1. Diagram and description of our initial architecture implementation

To be consistent with privacy best practices and reduce server uptime, this architecture uses the minimum amount of data the DS engine needs.

We filter out records that are lower than extremely low thresholds. Once these records are filtered out, around 40% of the data fits the criteria to be evaluated further. This reduces the server capacity needed by the DS engine by 60%.

To reduce false positives, we gather data before and after the timestamps where the extremely low thresholds are exceeded. We then evaluate the sensor data across this timespan and discard any sets with patterns of abnormal sensor readings or other false positive conditions. Figure 2 shows the time window we initially used.

Longitudinal acceleration versus time

Figure 2. Longitudinal acceleration versus time

Adjusting our initial architecture for better performance

Our initial design worked well for processing a few sample messages and achieved the desired near real-time delivery of the push notification. However, when the pipeline was enabled for over 1 million vehicles, certain limits were exceeded, particularly for Kinesis and Lambda integrations:

  • Our Kinesis GetRecords API exceeded the allowed five requests per shard per second. With each crash candidate retrieving an X-1 and X+1 message, we could only evaluate two per shard per second, which isn’t cost effective.
  • Additionally, the downstream SQS-reading Lambda function was limited to 10 records per second per invocation. This meant any slowdown that occurs downstream, such as during DS engine processing, could cause the queue to back up significantly.

To improve cost and performance for the Kinesis-related functionality, we abandoned the DynamoDB lookup table and the GetRecord calls in favor of using a Redis cache cluster on Amazon ElastiCache. This allows us to avoid all throughput exceptions from Kinesis and focus on scaling the stream based on the incoming throughput alone. The ElastiCache cluster scales capacity by adding or removing shards, which improves performance and cost efficiency.

To solve the Amazon SQS/Lambda integration issue, we funneled messages directly to an additional Kinesis stream. This allows the final Lambda function to use some of the better scaling options provided to Kinesis-Lambda event source integrations, like larger batch sizes and max-parallelism.

After making these adjustments, our tests proved we could scale to millions of vehicles as needed. Figure 3 shows a diagram of this final architecture.

Final architecture

Figure 3. Final architecture

Conclusion

Engineers across many functions worked closely to deliver the Collision Assistance product.

Our team of backend Java developers, infrastructure experts, and data scientists from TC and AWS built and deployed a near real-time product that helps Toyota and Lexus drivers document crash damage, file an insurance claim, and get updates on the actual repair process.

The managed services and serverless components available on AWS provided TC with many options to test and refine our team’s architecture. This helped us find the best fit for our use case. Having this flexibility in design was a key factor in designing and delivering the best architecture for our product.