Tag Archives: Technical How-to

Patch perfect: Automating Amazon Redshift patch testing

Post Syndicated from Eva Donaldson original https://aws.amazon.com/blogs/big-data/patch-perfect-automating-amazon-redshift-patch-testing/

Amazon Redshift continuously innovates to deliver improved performance and advanced features. In some releases, Amazon Redshift patches might introduce behavior changes. Testing patches in a non-production environment confirms that production workloads continue to function and you can maintain your applications’ service level agreements. As a best practice, keep Dev/QA clusters on the Current patch track and Production on the Trailing track. Test on Dev/QA when a patch lands, allowing 1–6 weeks of review before the scheduled production deployment.

In this post, we demonstrate an automated test suite that validates your Amazon Redshift cluster automatically after any patch, reboot, or modification. It uses standard drivers against real workload patterns to provide a verified gate between a patch landing and that patch reaching production.

Architecture

The solution uses native AWS services to create an automated validation pipeline.
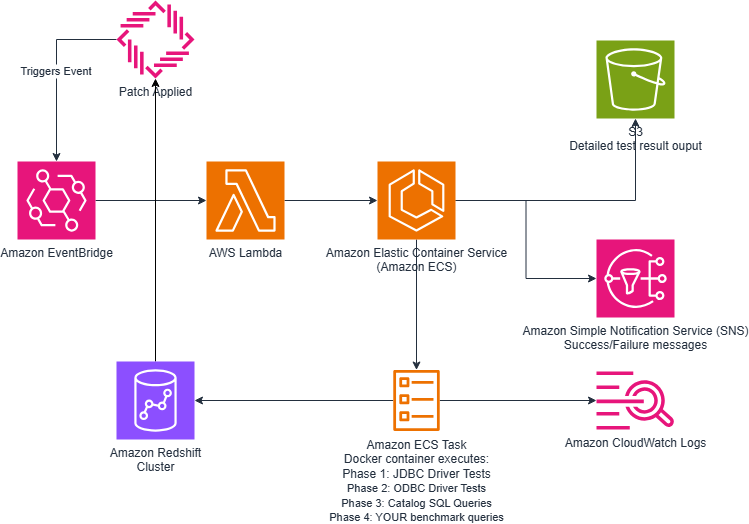
Architecture diagram of the patch testing pipeline: Amazon EventBridge triggers AWS Lambda, which runs an AWS Fargate task that tests the cluster and reports to Amazon S3 and Amazon SNS

Figure 1 — High-level architecture diagram
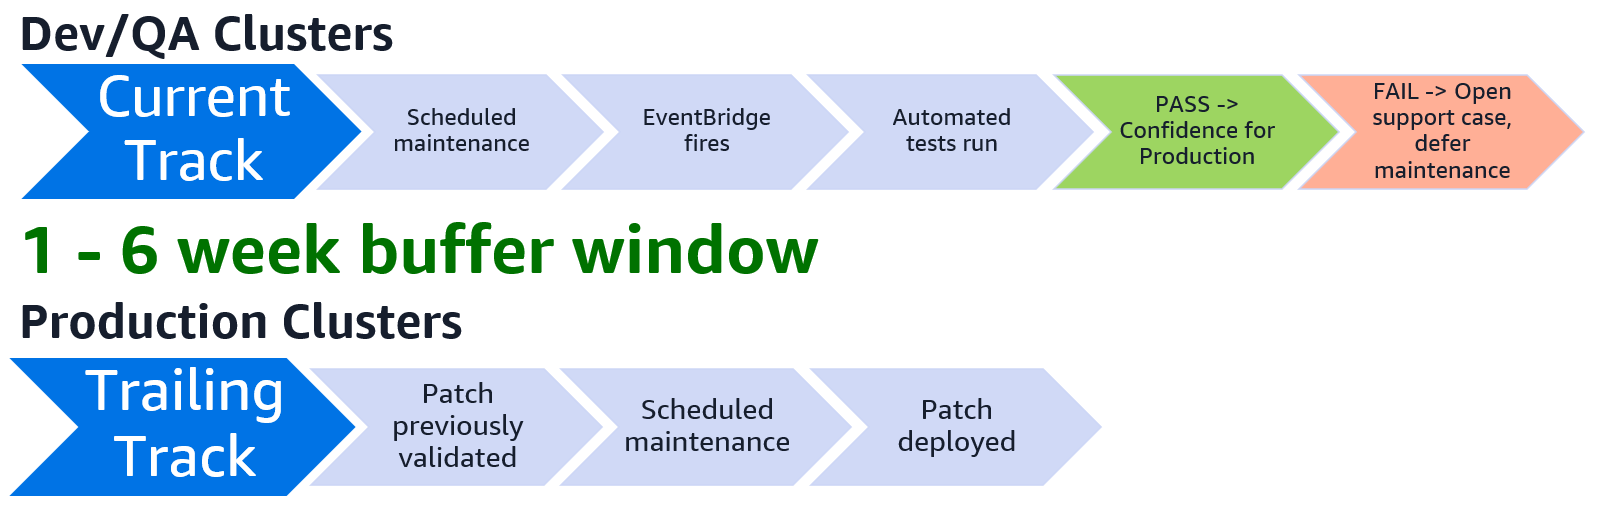
Process overview showing the four stages: event detection, orchestration, test execution, and reporting

Figure 2 — Process overview

  1. Event Detection: When your Amazon Redshift cluster receives a patch, reboot, or modification, the Amazon Redshift cluster event notifications fire. Amazon EventBridge rules match these events automatically.
  2. Orchestration: A lightweight AWS Lambda function receives the event from the Amazon EventBridge rule and launches an AWS Fargate task. The task runs in a subnet within the same Amazon Virtual Private Cloud (VPC) as your Amazon Redshift cluster, giving the test runner direct network connectivity to the cluster endpoint.
  3. Test Execution: A Docker container runs a comprehensive test suite in four phases:
    • JDBC Driver Tests – Validates the official Amazon Redshift JDBC driver, testing DatabaseMetaData API calls, connection handling, and queries that tools like SQL Workbench/J depend on.
    • ODBC Driver Tests – Validates the PostgreSQL ODBC driver with SQLTables, SQLColumns, and other ODBC API calls that RStudio and similar tools use.
    • Catalog SQL Queries – Runs approximately 35 queries against pg_catalog, information_schema, and svv_* views, organized by client (SQL Workbench, DBeaver, RStudio, JDBC metadata API).
    • Performance Benchmarks – Executes your custom workload queries and compares execution time against known baselines, flagging regressions. For convenience, the solution includes sample queries to be replaced with performance validation queries from your workloads.
  4. Reporting: Detailed JSON results land in Amazon Simple Storage Service (Amazon S3) for historical analysis. An Amazon Simple Notification Service (Amazon SNS) notification sends your team an email immediately with a pass/fail summary. Full JSON results are written to Amazon S3 with timing data for every individual query, row counts, error details, and the Amazon EventBridge event that triggered the run. If tests fail, you have specific, actionable evidence (which queries broke, which drivers failed, which benchmarks regressed) to open a support case requesting a rollback and defer maintenance until the case is resolved. When tests succeed, you can move forward with confidence to production.

For real-time feedback while the tests are running, a quick command tells you the current state:

aws lambda invoke --function-name my-redshift-tests-trigger \
--payload '{}' --cli-binary-format raw-in-base64-out /dev/stdout

What gets tested

The test suite covers two critical areas: client tool compatibility and query performance.

Client compatibility queries

The test suite replicates the connection behavior of popular SQL clients by issuing the same metadata API calls and queries they perform when connecting to your cluster.

Client What’s tested
SQL Workbench/J Connection queries, schema browsing, metadata enumeration
DBeaver Database object discovery, catalog traversal
RStudio (DBI/odbc) ODBC-specific catalog queries, column type mapping
JDBC Metadata API getTables(), getColumns(), getPrimaryKeys(), and other DatabaseMetaData method equivalents

The package contains the exact queries these clients execute upon connection.

Performance regression detection

The benchmark phase of the suite automatically detects whether it has been run before. On the first execution, it captures baseline query execution times as the “known good” state for your pre-patch environment. On every subsequent run, it compares current query timings against the stored baseline and flags any regressions. If a query that previously completed in 2 seconds now takes 15, the report calls it out immediately. This phase is designed to test your most performance-sensitive queries.

Prerequisites

Before deploying, make sure your environment meets the following requirements:

Docker installed. Consider building the image with AWS CloudShell, which comes with Docker pre-installed. You can do this either by uploading the customized repo to Amazon S3 and then downloading it to AWS CloudShell, or by cloning and customizing the repo directly within AWS CloudShell.

Getting started

The full solution is available on GitHub. It includes the AWS CloudFormation template, Docker build scripts, test suite, and documentation.

Clone the GitHub repo, customize it for your workload, deploy it against a Dev/QA cluster.

Detailed instructions are included in the package README.md. Reference those for deployment.

Step 1: Clone the repo

Clone the GitHub repo.

Step 2: Customize the scripts for your environment

The test suite ships with comprehensive default queries. After cloning and before deployment, edit the scripts as described in the following sections for each phase.

Add your performance-critical queries

Edit bundle/run_tests.py and replace the example queries with queries where performance is critical:

BENCHMARK_QUERIES = {
    "daily_patient_summary": """
SELECT department, COUNT(DISTINCT patient_id), AVG(los_days)
FROM clinical.encounters
WHERE admit_date >= CURRENT_DATE - 30
GROUP BY 1
""",
    "revenue_rollup": """
SELECT payer_type, SUM(total_charges)
FROM billing.claims
WHERE service_date >= DATE_TRUNC('month', CURRENT_DATE)
GROUP BY 1
""",
}

Add client-specific catalog queries

If your team uses custom views or schemas, add them to bundle/client_catalog_queries.py:

"custom_view_check": {
    "description": "Verify our reporting view works after patching",
    "sql": "SELECT * FROM analytics.monthly_kpis LIMIT 10",
},

Step 3: Build the Docker image

Execute build-image.sh, which creates an Amazon ECR repository, builds the Docker image (with JDBC and ODBC drivers bundled), and pushes it, outputting the image URI for the next step.

# Upload project to S3, then build in CloudShell
./build-image.sh --stack-name my-redshift-tests

Step 4: Deploy the stack

Use the AWS Command Line Interface (AWS CLI) to deploy the AWS CloudFormation stack with your environment-specific parameters. The stack creates the required components: Amazon Elastic Container Service (Amazon ECS) cluster, AWS Fargate task definition, security groups, VPC endpoints (to keep AWS Secrets Manager and Amazon SNS traffic off the NAT gateway), Amazon S3 bucket, Amazon SNS topic, AWS Lambda trigger, and Amazon EventBridge rules.

aws cloudformation deploy \
--template-file template.yaml \
--stack-name my-redshift-tests \
--parameter-overrides \
RedshiftSecretArn=arn:aws:secretsmanager:... \
RedshiftHost=my-cluster.xxxx.us-east-2.redshift.amazonaws.com \
RedshiftClusterIdentifier=my-cluster \
VpcId=vpc-xxxxxxxx \
VpcSubnetIds=subnet-aaa,subnet-bbb \
RedshiftSecurityGroupId=sg-xxxxxxxx \
EcrImageUri=123456789012.dkr.ecr.us-east-2.amazonaws.com/my-redshift-tests-runner:latest \
[email protected] \
--capabilities CAPABILITY_NAMED_IAM

Key takeaways

Here are the core principles that make automated patch testing effective:

  1. Dev/QA on Current track, Production on Trailing: This separation creates the buffer window between when a patch is available and when it reaches production. Without it, there’s no opportunity to catch regressions before they affect users.
  2. Automate the validation: The track split is most effective if the test suite runs after every patch. Event-driven automation helps confirm no patch goes untested during the buffer window.
  3. Test with real drivers: Simulated queries aren’t sufficient. The test suite exercises the Amazon Redshift JDBC and PostgreSQL ODBC drivers that your SQL clients depend on. This validates the same code paths your tools use in production.
  4. Event-driven, not scheduled: Tests run the moment a patch is applied. They don’t run on a fixed cron schedule. Patch applied, then test executed, then results delivered in minutes.
  5. Low operational overhead, minimal cost: The entire solution is serverless (AWS Lambda and AWS Fargate). There are no instances to manage and no agents to install. The Fargate task spins up only when a patch event fires, runs the test suite, and shuts down. You pay only for the compute each test run consumes.

Clean up

When you no longer need the automated test suite, delete the associated resources so you don’t incur ongoing costs.

  1. Delete any created prerequisites, if not needed.
    1. Amazon Redshift cluster (removes the managed secret).
    2. NAT gateway.
    3. VPC.
  2. Empty the Amazon S3 results bucket (AWS CloudFormation cannot delete non-empty buckets).
  3. Delete the image you installed in the Amazon ECR repository in step 1 of getting started.
  4. Delete the AWS CloudFormation stack to remove the Amazon ECS cluster, AWS Fargate task definition, security groups, VPC endpoints, Amazon S3 bucket, Amazon SNS topic, AWS Lambda function, and Amazon EventBridge rules created by the deployment.
    aws cloudformation delete-stack --stack-name my-redshift-tests

Conclusion

Automated patch testing ensures consistent and predictable performance of your production workloads. By deploying Dev/QA clusters on the Current track with event-driven validation, you gain weeks of advance notice before patches reach production. The solution presented here provides comprehensive testing of JDBC drivers, ODBC drivers, catalog queries, and performance benchmarks. It requires zero manual intervention. Deploy it once, customize it for your workload, and gain confidence that the next Amazon Redshift patch will be validated before it matters.

To learn more about Amazon Redshift, explore the following resources:


About the author

Eva Donaldson

Eva Donaldson

Eva is a Senior Technical Account Manager (TAM) at AWS, specializing in Healthcare & Life Sciences customers. With 20+ years of experience as a data architect, engineer, and team manager, she focuses on designing automated data platforms and solutions that solve real business problems.

Authenticate legitimate AI agent traffic with AWS WAF Bot Control

Post Syndicated from Harith Gaddamanugu original https://aws.amazon.com/blogs/security/authenticate-legitimate-ai-agent-traffic-with-aws-waf-bot-control/

As AI agents and automated tools increasingly access web applications, distinguishing legitimate bot traffic from malicious attempts has become a critical security challenge. Traditional approaches such as IP-based filtering and reverse DNS lookups fail in multi-tenant systems (such as Amazon Bedrock AgentCore) where thousands of distinct workloads share the same IP space. Attackers can easily spoof user agents, and manual allowlists don’t scale with growing demand.

Web Bot Authentication (WBA), available in AWS WAF Bot Control since November 2025, solves this challenge by implementing cryptographic signatures that provide tamper-proof verification of bot identities. WBA uses asymmetric cryptography to verify that a request comes from an authorized automated agent, relying on two active Internet Engineering Task Force (IETF) drafts: a directory draft for sharing public keys, and a protocol draft defining how keys attach crawler identity to HTTP requests.

With WBA, you can confidently identify trusted automated access while maintaining granular control through WAF labels, creating a more secure and manageable ecosystem for both bot operators and website owners. AWS WAF Bot Control respects WBA verification status by default, automatically allowing verified AI agent traffic.

This post provides a deeper technical guide to implementing WBA with AWS WAF. You learn how WBA works, explore the new labels and capabilities it introduces, and walk through a step-by-step implementation—including signing code—to authenticate bot traffic using cryptographic signatures.

How Web Bot Authentication works with AWS WAF

WBA uses asymmetric cryptography to verify bot identities through HTTP message signatures. The process works as follows:

  1. Bot registration – Bot operators publish their public keys in a signature directory. AWS WAF regularly polls these directories and maintains a valid key registry.
  2. Request signing – Each bot operator’s request is signed using their private key following the IETF standard HTTP Message Signatures (RFC 9421).
  3. Verification – AWS WAF verifies signatures against known public keys associated with the bot operator and appends labels related to verification status.

A typical WBA-signed request includes headers like the following:

Signature-Agent: https://signature-agent.test
Signature-Input: sig2=("@authority" "signature-agent")
;created=1735689600
;keyid="poqkLGiymh_W0uP6PZFw-dvez3QJT5SolqXBCW38r0U"
;alg="ed25519"
;expires=1735693200
;nonce="e8N7S2MFd/qrd6T2R3tdfA..."
;tag="web-bot-auth"
Signature: sig2=:jdq0SqOwHdyHr9+r5jw3iYZH6aNGKijYp/EstF4RQ..

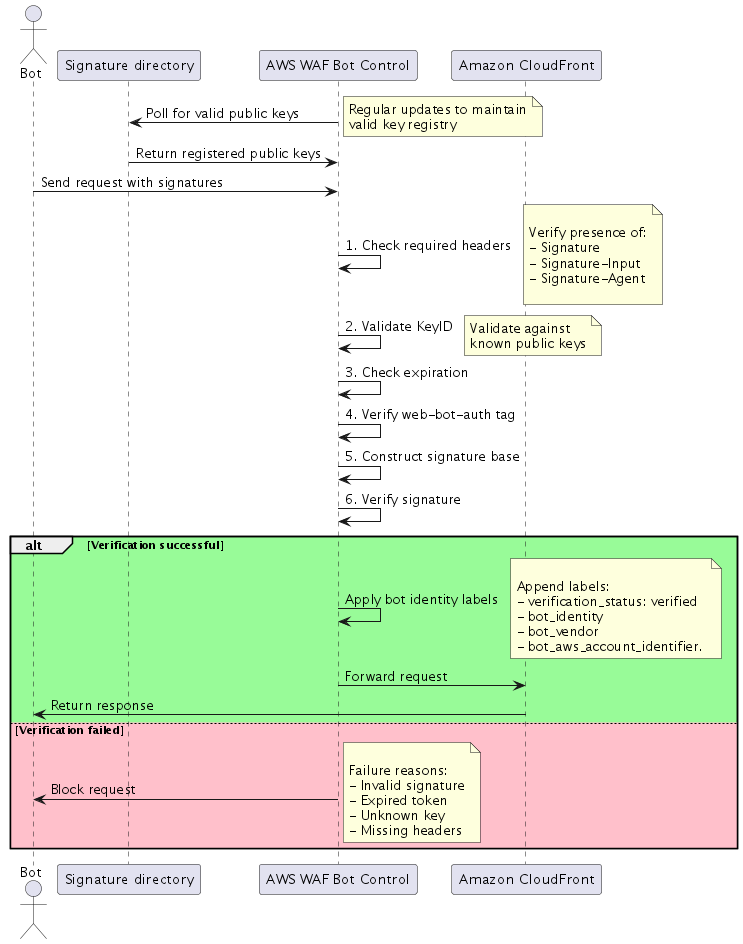
The following sequence diagram shows how AWS WAF verifies bot signatures and applies labels for allow or block decisions.

Figure 1 – AWS WAF Web Bot Authentication verification flow

Figure 1 – AWS WAF Web Bot Authentication verification flow

The workflow shown in figure 1 includes the following steps:

  1. A bot sends a signed request to Amazon CloudFront and is inspected by AWS WAF Bot Control
  2. AWS WAF Bot Control retrieves the bot operator’s public key from the signature directory
  3. AWS WAF Bot Control verifies the ed25519 signature
  4. AWS WAF Bot Control appends a verification label (verified, invalid, expired, or unknown_bot)

AWS WAF Bot Control evaluates rules using the label to allow or block the request.

New capabilities added to AWS WAF

With the addition of WBA, the following capabilities were added to AWS WAF.

Cryptographic bot verification

When a bot sends a request, it includes HTTP message signatures that AWS WAF validates at the edge using the AWS WAF Bot Control rule group (version 4.0 and later). This validation process adds minimal latency to requests while providing cryptographic certainty about the bot’s identity. HTTP Message Signatures is an open IETF standard (RFC 9421) that defines a mechanism for signing and verifying HTTP messages using asymmetric keys—in practice, this means a bot cryptographically signs specific headers and metadata of each request, and the receiver can verify the signature using the bot’s published public key.

New labels within AWS WAF for granular control

AWS WAF automatically validates signatures, and successfully validated traffic is immediately marked as verified. This verification status can be used in WAF rules and bot management policies, giving you the ability to write your own rules based on the new functionality.

The following table describes the new labels.

Label Meaning Suggested action
awswaf:managed:aws:bot-control:bot:web_bot_auth:verified Successful cryptographic verification Allow
awswaf:managed:aws:bot-control:bot:web_bot_auth:invalid Failed verification attempt Block or rate-limit
awswaf:managed:aws:bot-control:bot:web_bot_auth:expired Expired key used Block and alert
awswaf:managed:aws:bot-control:bot:web_bot_auth:unknown_bot Unrecognized key Monitor or block
awswaf:managed:aws:bot-control:bot:vendor:<vendor_name> Bot vendor or operator Use for vendor-specific rules
awswaf:managed:aws:bot-control:bot:name:<rfc_name> Bot name (RFC token from WBA) Use for bot-specific rules
awswaf:managed:aws:bot-control:bot:account:<hash> AWS account identifier (Amazon Bedrock AgentCore agents only) Use for account-level controls

AWS WAF now automatically allows verified AI agent traffic

AWS WAF Bot Control now respects WBA verification status by default, automatically allowing verified AI agent traffic. This includes two specific behavior changes:

  • Category:AI rule update – Previously, the Category:AI rule under common Bot Control blocked unverified bots. Bot Control now checks WBA verification status before applying this rule.
  • TGT_TokenAbsent rule update – The TGT_TokenAbsent rule, which detects requests without a WAF token, no longer matches requests that carry the web_bot_auth:verified label.

Key benefits for AWS WAF customers

WBA with AWS WAF delivers several advantages for organizations managing automated traffic at scale.

  • Enhanced bot visibility – Clear identification of distinct bots operating from multi-tenant platforms like Amazon Bedrock AgentCore, providing transparency into automated traffic sources. The AWS WAF console includes a new AI activity dashboard that provides a centralized view of AI bot and agent traffic across your protected resources.
  • Enhanced security – Cryptographic verification of bot identities using industry-standard signing mechanisms.
  • Reduced false positives – Accurate distinction between legitimate and malicious automated traffic, particularly in shared IP environments.
  • Industry alignment – Alignment with industry standards and major content delivery network (CDN) providers for consistent bot authentication across platforms.

Customer use cases for WBA with AWS WAF

Across industries, organizations use WBA to grant automated agents secure, controlled access to their web applications. The following scenarios highlight where this capability delivers real-world value:

  • Verified customer support agents – Authenticate AI-powered chat and support bots so websites can recognize them as approved, registered agents. This enables seamless customer service automation while maintaining security controls and audit trails.
  • Automated crawling and indexing – Allow search engine crawlers and content indexers to fetch pages with clear identity and scoped permissions. This reduces false-positive blocks, improves crawl efficiency, and helps legitimate bots access your content without triggering security controls.
  • Partner integrations – Third-party agents can access customer portals and APIs with explicit consent and granular, scoped access controls. This facilitates secure business-to-business (B2B) integrations while maintaining visibility into partner bot activity.
  • Enterprise automations and agents – Internal automation tools—including monitoring systems, QA bots, continuous integration and delivery (CI/CD) pipelines, and robotic process automation (RPA) solutions—get authenticated access to web applications with least-privilege access principles and full auditability.

Availability

WBA was introduced in Bot Control rule group Version_4.0 (November 2025) for Amazon CloudFront distributions, with continued support in later versions. With Version_6.0, WBA is available for resource types supported by AWS WAF across standard commercial AWS Regions.

Getting started: Developers or agents quick start

Whether you’re implementing WBA yourself or working with an AI coding assistant, the following steps walk you through deploying WBA, signing requests, and writing custom rules.

Step 1: Deploy the WBA-enabled Bot Control

Add the AWS WAF Bot Control rule group to your CloudFront-associated web ACL using static Version_4.0 or Version_5.0—both include WBA support for cryptographic bot verification. Version_5.0 (released February 2026) covers more than 650 unique bots and agents spanning categories including AI search engine crawlers, AI data collectors, AI assistants, and large language model (LLM) training crawlers.

Important: You must explicitly select one of these static versions.

The following example CloudFormation YAML snippet shows a bot control rule set configuration:

# Bot Control rule group with WBA support
ManagedRuleGroupStatement:
  VendorName: AWS
  Name: AWSManagedRulesBotControlRuleSet
  # Use Version_4.0 or higher for WBA support
  Version: Version_5.0
  ManagedRuleGroupConfigs:
    - AWSManagedRulesBotControlRuleSet:
        # COMMON level provides WBA verification
        # TARGETED level adds additional bot-specific protections
        InspectionLevel: COMMON

Step 2: Sign requests from your bot

If your agent runs on Amazon Bedrock AgentCore Browser, request signing is handled automatically—no additional configuration is required.

For agents running outside of AgentCore, registration APIs are on the roadmap that you can use to sign requests independently by:

  1. Generating an ed25519 key pair
  2. Hosting your public key in a signature directory
  3. Signing outbound HTTP requests using the Signature-Input and Signature headers with the web-bot-auth tag. For language-specific signing implementations, see the HTTP Message Signatures RFC (RFC 9421) and the AWS WAF Bot Control documentation.

Step 3: Write custom rules using WBA labels

Use the verification labels in custom WAF rules for granular traffic control, for example:

  • Allow – awswaf:managed:aws:bot-control:bot:web_bot_auth:verified
  • Rate-limit – awswaf:managed:aws:bot-control:bot:web_bot_auth:invalid
  • Alert on – awswaf:managed:aws:bot-control:bot:web_bot_auth:expired

Step 4: Monitor WBA traffic

Use AWS WAF metrics and logs to monitor authenticated bot traffic:

  • Review Amazon CloudWatch metrics for Bot Control rule group matches and set up alarms for anomalous or unexpected spikes in invalid or expired verification attempts.
  • Analyze AWS WAF logs to identify patterns in bot authentication attempts and filter on web_bot_auth labels.
  • Use the AI Activity Dashboard in the AWS WAF console for a centralized view of AI bot traffic. Visualize traffic trends, identify top bots and frequently targeted paths, and filter by verification status to decide which bots to allow, rate-limit, or block.

Conclusion

WBA with AWS WAF provides a cryptographically secure, standards-based approach to authenticating legitimate AI agent traffic. By moving from IP-based allowlisting to signature-based verification, you gain accurate bot identification that works across multi-tenant environments.

Looking ahead, our focus is to simplify bot authentication and make it safer by default. Registration APIs that agent owners can use to cryptographically verify bot identity and intent are on the roadmap, helping website owners quickly distinguish trusted automation from unknown traffic.

If you own an agent, adopt WBA and register your agent to receive verified status. In parallel, AWS continues to actively participate in the IETF web-bot-auth working group, advocating for complementary approaches—using both identifying and anonymous verification protocols—and will incorporate these standards into products as they mature to help your deployments stay aligned with the broader ecosystem.

To get started, see the AWS WAF Bot Control documentation and the HTTP Message Signatures RFC (RFC 9421).

If you have feedback about this post, submit comments in the Comments section below.


Harith Gaddamanugu

Harith Shantan Gaddamanugu

Harith is a Sr Edge Specialist Solutions Architect at AWS, where he architects critical infrastructure and security solutions that serve millions of users globally. With a decade of expertise in cloud perimeter protection and web acceleration, he guides large enterprises building resilient architectures. Outside work, Harith enjoys hiking and landscape photography with his family.

Author

Kaustubh Phatak

Kaustubh is a product leader specializing in AI/ML systems and enterprise security solutions. He has led cross-functional teams in deploying AI-powered products at scale, working closely with security architects and CISOs to address the intersection of AI innovation and cybersecurity risk. His work focuses on translating complex technical capabilities into business value, particularly in emerging technology domains where traditional frameworks don’t apply.

Automated Incident Remediation with AWS DevOps Agent and Kiro CLI

Post Syndicated from Jishnu Dasgupta original https://aws.amazon.com/blogs/devops/automated-incident-remediation-with-aws-devops-agent-and-kiro-cli/

Introduction

Automated incident remediation – turning investigation findings into deployed fixes without manual toil – is the next frontier for operations teams running distributed workloads on AWS. Today, when an incident fires at 2 AM, the on-call engineer must correlate telemetry across Amazon CloudWatch, deployment pipelines, and application logs, then manually write and deploy a fix – a process that routinely takes hours. AWS DevOps Agent addresses the first half by autonomously investigating incidents, identifying root causes, and generating mitigation plans in minutes. During preview, customers and partners reported up to 75% lower MTTR, 80% faster investigations, and 94% root cause accuracy.

But investigation and mitigation recommendations are only half the story. Someone still has to read the findings, write the fix, test it, and deploy it. What if that second half could be automated too?

In a previous post, Leverage Agentic AI for Autonomous Incident Response with AWS DevOps Agent, we demonstrated how to configure AWS DevOps Agent to monitor your applications, trigger autonomous investigations, and follow best practices for production deployments. We also published this code sample which demonstrates how investigations could be wired to be triggered automatically when a Amazon CloudWatch alarm is raised. These two articles now allow you to trigger AWS DevOps Agent investigation on a Amazon CloudWatch alarm and produce a mitigation plan.

In this post, we demonstrate how to integrate AWS DevOps Agent mitigation plan output with Kiro CLI – running in headless mode on AWS CodeBuild – to close the remediation loop end-to-end. When AWS DevOps Agent completes a mitigation analysis, an event-driven pipeline automatically routes the findings to Kiro CLI, which applies the fix to your codebase, creates a pull request for human review, and triggers deployment upon approval. The result: L1/L2 incidents go from detection to deployed fix with minimal manual intervention – the only human touchpoint is the pull request approval.

We walk through the complete solution using a sample CloudFormation application, including the infrastructure code, anomaly generation scripts, event routing, and the Kiro CLI steering configuration that makes it all work. All source code is available in the accompanying aws-samples repository.

Solution Overview

Consider a typical web application running on AWS — a frontend behind an Application Load Balancer, backend compute on Amazon EC2, and an Amazon RDS database, with source code and CloudFormation templates in AWS CodeCommit. When something goes wrong in this environment, the solution chains two AWS frontier agents —AWS DevOps Agent for autonomous investigation and mitigation, and Kiro CLI for automated code remediation — through a fully serverless event-driven bridge to take the application from incident to deployed fix.

Solution Architecture

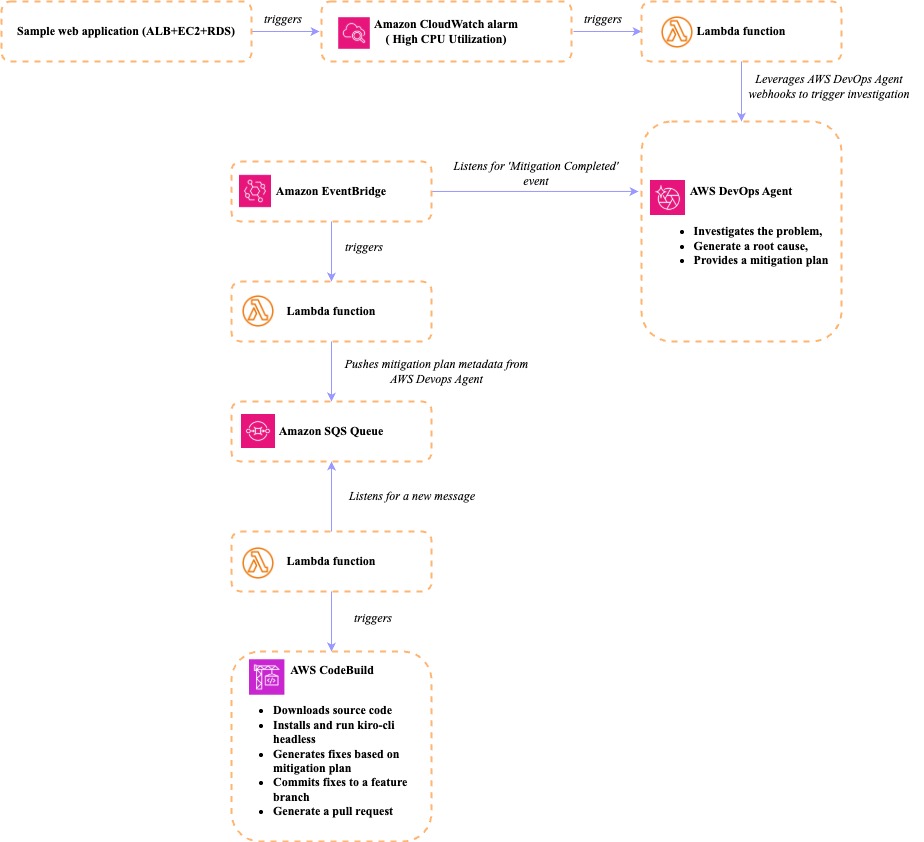
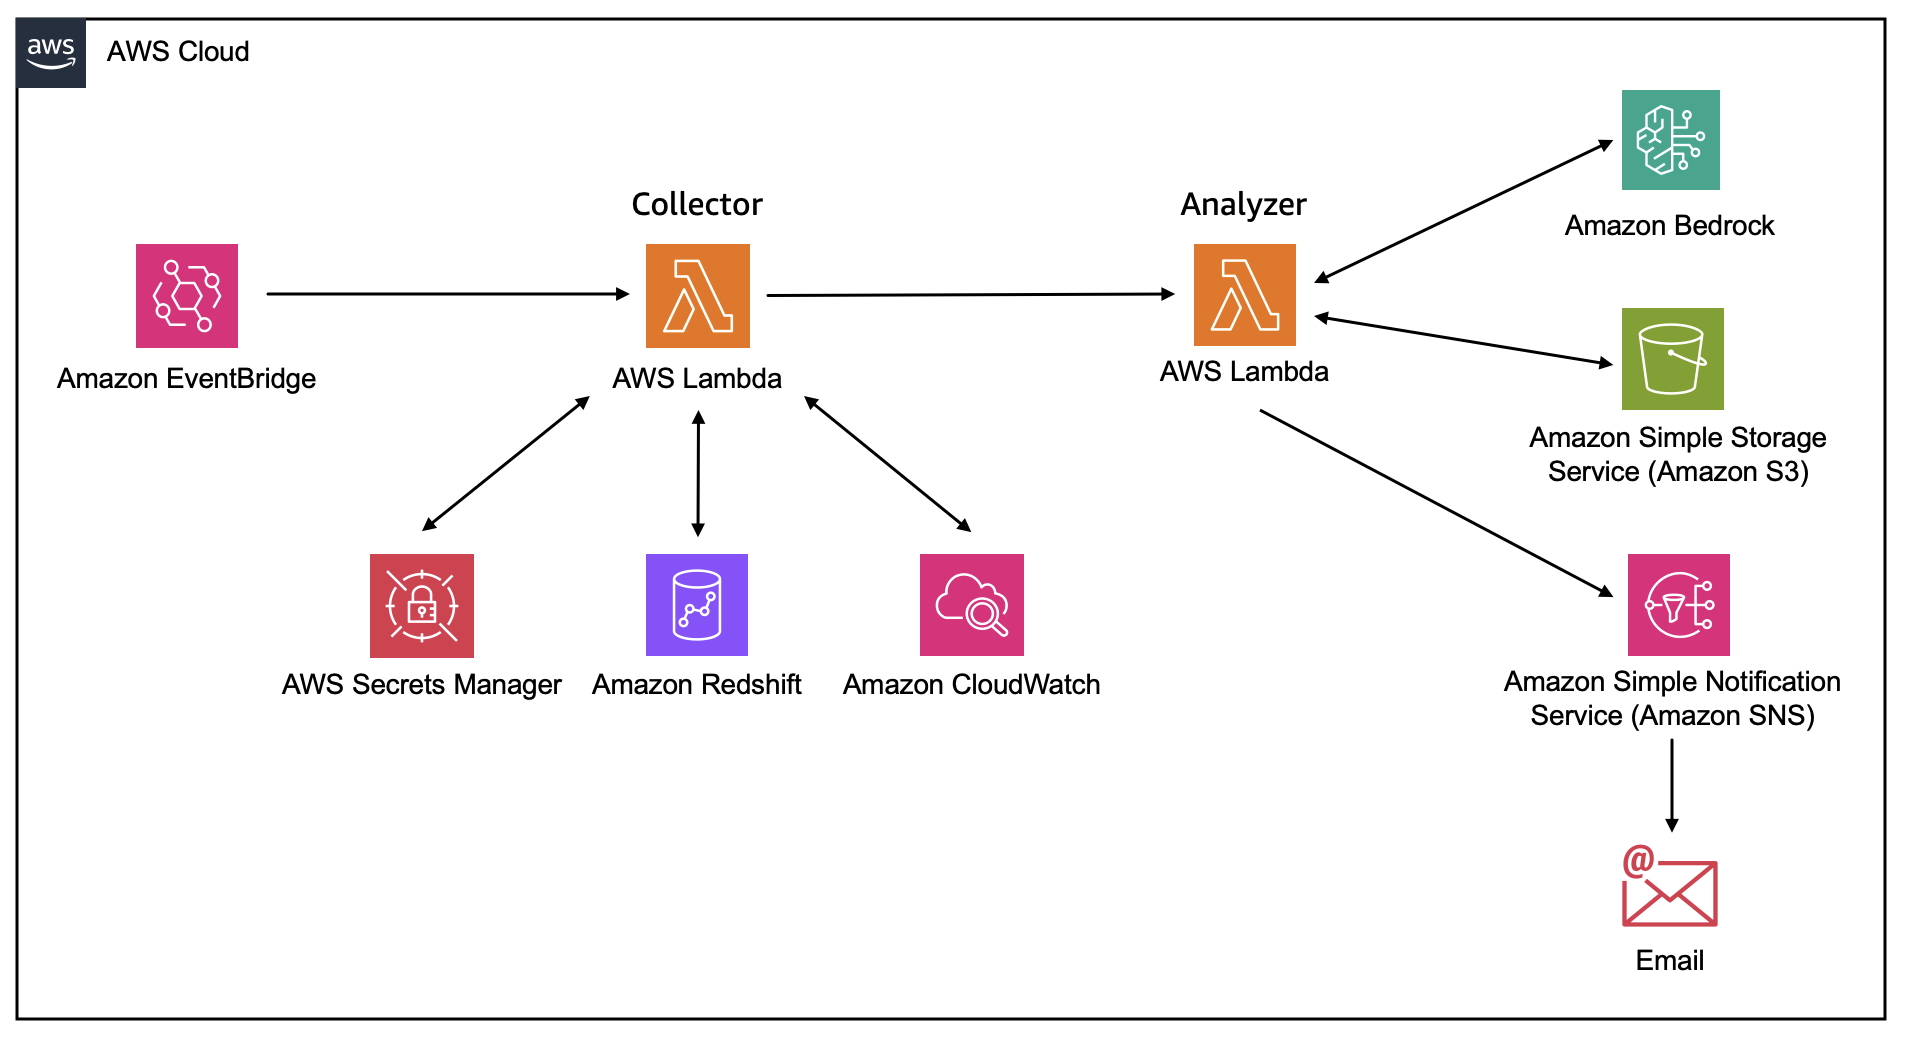
Fig 1 – Solution architecture

How it works

  1. An incident occurs – Your application experiences an issue – high CPU utilization, elevated error rates, slow response times. Amazon CloudWatch alarms fire.
  2. DevOps Agent investigates – AWS DevOps Agent, which has your application onboarded into an Agent Space, autonomously correlates metrics, logs, and deployment history to identify root cause and generate a mitigation plan.
  3. EventBridge routes the signal – An Amazon EventBridge rule captures Mitigation Completed events (source: aws.aidevops) and invokes a AWS Lambda function.
  4. Lambda extracts and queues – The AWS Lambda function calls the AWS DevOps Agent API to retrieve the mitigation summary and execution plan, then publishes the payload to Amazon SQS queue.
  5. CodeBuild runs Kiro CLI – When a message arrives in the Amazon SQS queue, a AWS Lambda function with an SQS event source mapping triggers a AWS CodeBuild execution, passing the message content as an environment variable. AWS CodeBuild runs Kiro CLI in headless mode (–no-interactive –trust-tools=read,write,grep,shell), using the mitigation payload as a remediation prompt.
  6. Kiro CLI applies the fix – Guided by a steering file that describes the repository structure and remediation conventions, Kiro CLI modifies the CloudFormation template or application code, commits to a feature branch, and creates a pull request.
  7. Human approves, pipeline deploys – A developer reviews the pull request. Upon approval and merge, the associated deployment pipeline gets triggered to execute the change.

Prerequisites

To follow along with this walkthrough, you need:

  • An AWS account for AWS DevOps Agent access
  • An Agent Space configured
  • Kiro CLI with a Pro, Pro+, or Power subscription (required for headless mode API keys)
  • AWS CLI configured with appropriate credentials
  • The sample repository pushed to your account’s AWS CodeCommit repository
Once completed, follow along the Readme file to setup the components which allow you to implement and execute the above architecture. The sections below provide an explanation of the components that have been built to support the architecture.

Capturing mitigation events

AWS DevOps Agent publishes lifecycle events to the Amazon EventBridge default event bus whenever an investigation or mitigation changes state. Each event uses the source aws.aidevops and a detail-type that identifies the specific like Mitigation Completed, Investigation Completed, or Mitigation Failed. The post focuses on a single signal: the moment a mitigation finishes successfully.

EventBridge rule and Lambda extraction

An Amazon EventBridge rule matching the Mitigation Completed detail-type invokes a AWS Lambda function. The event payload contains metadata (agent_space_id, task_id, and execution_id) which allows the AWS Lambda function to call the AWS DevOps Agent and extracts two key objects: the mitigation summary (what action to take and why) and the execution plan (step-by-step instructions). It publishes this structured payload to an Amazon SQS queue for downstream processing.

Headless remediation with Kiro CLI

With mitigation payloads landing in the Amazon SQS queue, we need a compute environment that can check out the application and infrastructure repository, run Kiro CLI agent against the codebase, and push changes back. AWS CodeBuild is a natural fit — it provides on-demand compute, integrates natively with AWS CodeCommit and requires no persistent infrastructure.

Kiro CLI 2.0 introduced headless mode, which allows it to run programmatically in deployment pipelines without an interactive terminal. You authenticate with an API key (stored in AWS Secrets Manager), pass a prompt, and Kiro CLI executes end-to-end — same tools, same agents, same capabilities as the interactive experience.

How CodeBuild orchestrates the fix

When a message arrives in the Amazon SQS queue, a trigger AWS Lambda function starts a AWS CodeBuild execution, passing the Amazon SQS message body as an environment variable. The AWS CodeBuild buildspec follows a straightforward sequence:

  1. Install : Installs Kiro CLI and configures the environment. The KIRO_API_KEY is pulled automatically from AWS Secrets Manager ,never hardcoded.
  2. Generate prompt : A Python script converts the structured mitigation payload into a natural-language remediation prompt. It inspects the content to classify whether the change targets infrastructure (or application code, then generates a focused prompt with the action, reasoning, and specific instructions.
  3. Create feature branch : Checks out a new branch named after the agent space and execution IDs for traceability.
  4. Run Kiro CLI : Invokes Kiro CLI chat –no-interactive –trust-tools=read,write,grep,shell with the generated prompt. The –trust-tools flag auto-approves specific tool categories following least-privilege, since there is no human to confirm.
  5. Validate and commit : Guardrails check the changes: file count limits, protected file detection, Python syntax validation (py_compile), and YAML linting. If all checks pass, the changes are committed and pushed.
  6. Create pull request : Creates an AWS CodeCommit pull request with the mitigation action as the title and the AWS DevOps Agent reasoning in the description.

The steering file

What makes Kiro CLI effective at remediation – rather than just generating generic code – is the steering file. Steering gives Kiro persistent knowledge about your project: repository structure, coding conventions, and decision frameworks.
For this solution, the steering file serves as the guardrails for automated remediation. It defines:

  • Repository structure – Maps each directory to its purpose.
  • Decision framework – Rules for classifying changes as infrastructure vs. application.
  • Scope constraints – Maximum 3 files per remediation, no new files, no new dependencies, no deletions.
  • Protected files – The buildspec, infrastructure pipeline templates, bridge code, and steering files themselves are explicitly off-limits.
  • Fail-safe – If the prompt is ambiguous or Kiro cannot determine what to change, it makes no changes rather than guessing.

This steering file is committed to the repository, so every AWS CodeBuild execution picks it up automatically. It ensures Kiro CLI makes targeted, predictable changes rather than broad refactors.

From pull request to deployment

At this point, the automated pipeline has done its work – Kiro CLI has analyzed the mitigation plan, modified the appropriate files, and created a pull request on a feature branch. The pull request description includes what was changed, why (directly from the AWS DevOps Agent’s reasoning), and the agent space and execution IDs for full traceability back to the original incident.

This is where the human-in-the-loop gate comes in. A developer reviews the pull request -verifying that the change is correct, scoped appropriately, and safe to deploy. This approval step is deliberate: while we trust the agents to investigate, analyze, and propose fixes, a human makes the final deployment decision.

Once the pull request is approved and merged into the main branch, the deployment pipelines implement the approved changes in the target environment.

The entire cycle – from CloudWatch alarm to deployed fix – completes in minutes rather than hours, with the only manual step being the pull request review. For organizations handling high volumes of L1/L2 incidents, this translates directly into reduced operational toil and faster recovery.

Cleanup

To avoid ongoing charges, remove the resources created during this walkthrough. Refer to the Readme for the complete teardown sequence.

Conclusion

In this post, we demonstrated how to integrate AWS DevOps Agent mitigation outputs with [1] Kiro CLI to build a closed-loop incident remediation pipeline. By connecting these two frontiers agents’ operations teams can go from incident detection to deployed fix with a single human touchpoint: the pull request approval.

This approach delivers measurable impact for enterprise operations:

  • Reduced MTTR – L1/L2 incidents that previously required hours of manual investigation and remediation can now resolve in minutes.
  • Improved operator productivity – Engineers shift from reactive firefighting to reviewing and approving targeted, AI-generated fixes.
  • Consistent remediation – Steering files codify your team’s conventions and decision frameworks, ensuring every automated fix follows the same standards regardless of when or how often incidents occur.

Ready to get started? Clone the aws-samples repository for the complete implementation, visit the AWS DevOps Agent documentation to configure your first Agent Space, and explore the Kiro CLI documentation to learn more about steering-file-driven code generation. Have questions or want to share how you’ve adapted this pattern? Leave a comment below or open an issue in the repository
Jishnu Dasgupta

Jishnu Dasgupta

Jishnu Dasgupta is a Senior Solutions Architect at AWS who specializes in manufacturing and automotive domain. His focus areas are building, migrating and modernizing applications on AWS. He leverages his expertise and experience to help AWS customers build optimized, scalable and fit to purpose architecture on AWS.

Chetan Dharma

Chetan Dharma

Chetan Dharma is a Senior AI Solution architect with 20+ years of experience driving technology transformation for large-scale global enterprises. He has worked across investment banking, logistics, automative, and digital native businesses — progressing from hands-on engineering to architecture to advising AI transformation

Cut costs and simplify operations with writable warm storage in Amazon OpenSearch Service

Post Syndicated from Bharav Patel original https://aws.amazon.com/blogs/big-data/cut-costs-and-simplify-operations-with-writable-warm-storage-in-amazon-opensearch-service/

Managing petabytes of search data means making tough choices: keep everything fast and expensive, or make it affordable but read-only. UltraWarm is a proven, cost-effective solution for read-heavy historical data. However, some workloads occasionally need to update historical records, such as late-arriving data or compliance corrections. With UltraWarm, you must migrate those indices back to hot, perform the update, and migrate back. What if you could write directly to your cost-effective warm storage instead?

In this post, I show you how writable warm storage removes the costly migration cycle. You can reduce your infrastructure costs by up to 48 percent and update historical data in seconds instead of hours. I walk through a real-world cost comparison and performance benchmarks, and help you decide when to use writable warm versus UltraWarm.

The challenge with tiered storage

Amazon OpenSearch Service handles data-intensive search and analytics workloads, from real-time log analytics and application monitoring to security event detection. As your data volumes grow from terabytes to petabytes, you face a fundamental question: how do you keep recent data fast while making earlier data affordable?

OpenSearch Service addresses this with a tiered storage architecture:

  • Hot – Highest performance for active indexing and search using instance-attached storage.
  • UltraWarm – Cost-effective, read-only tier backed by Amazon Simple Storage Service (Amazon S3) with local caching for less frequently queried data.
  • Cold – Fully detached from the cluster, with the lowest cost for rarely accessed data. Cold indices must be migrated back to UltraWarm or hot before any reads or writes can be performed.

For immutable log data, this model works well. However, a specific class of workloads hits its limitations when they occasionally need to write to earlier data, and read-only becomes a bottleneck.

Prerequisites

To use writable warm storage, you need the following:

  1. An Amazon OpenSearch Service domain running version 3.3 or later.
  2. OpenSearch Optimized (OI2) instance family support in your AWS Region.
  3. Workloads with a minimum 5-second refresh interval.
  4. Data nodes using the OpenSearch Optimized instance family (OR2 for hot, OI2 for warm).

Note: Writable warm doesn’t currently support the cold storage tier.

The UltraWarm bottleneck

With UltraWarm, updating even a single document requires migrating the index back to hot, performing the write, and migrating it back. This round trip involves a force merge (consolidating index segments), snapshot creation, and shard relocation. These operations consume significant CPU, memory, and disk space on your hot nodes, and they take approximately 130 minutes per 100 GB index. This time was measured on a domain with 3 × r6g.2xlarge hot nodes, 3 × ultrawarm1.large warm nodes, and 3 dedicated leader nodes (US East, N. Virginia), using a single-shard index with one replica. Actual times vary based on domain configuration, shard count, segment count, hot node utilization, and migration queue depth. The result is that you over-provision hot nodes, build complex pipelines, or keep data in hot longer than necessary, which increases cost and complexity.

Introducing writable warm storage

OpenSearch Service now offers writable warm nodes that use OpenSearch Optimized (OI2) instances, the same instance family that powers durable, Amazon S3-backed storage on hot nodes. Because data is already persisted on Amazon S3, tier transitions become a lightweight shard relocation rather than a resource-intensive migration. The Lucene engine, which is OpenSearch’s underlying search library, operates identically on both tiers. As a result, writable warm nodes support active writes, background merges, and periodic refreshes, just like hot nodes.

Late-arriving data, compliance backfills, and corrections that previously required a warm-to-hot-to-warm round trip now resolve with a direct write in seconds. There is no force merge, no snapshot, no shard relocation, and no hot node resource consumption.

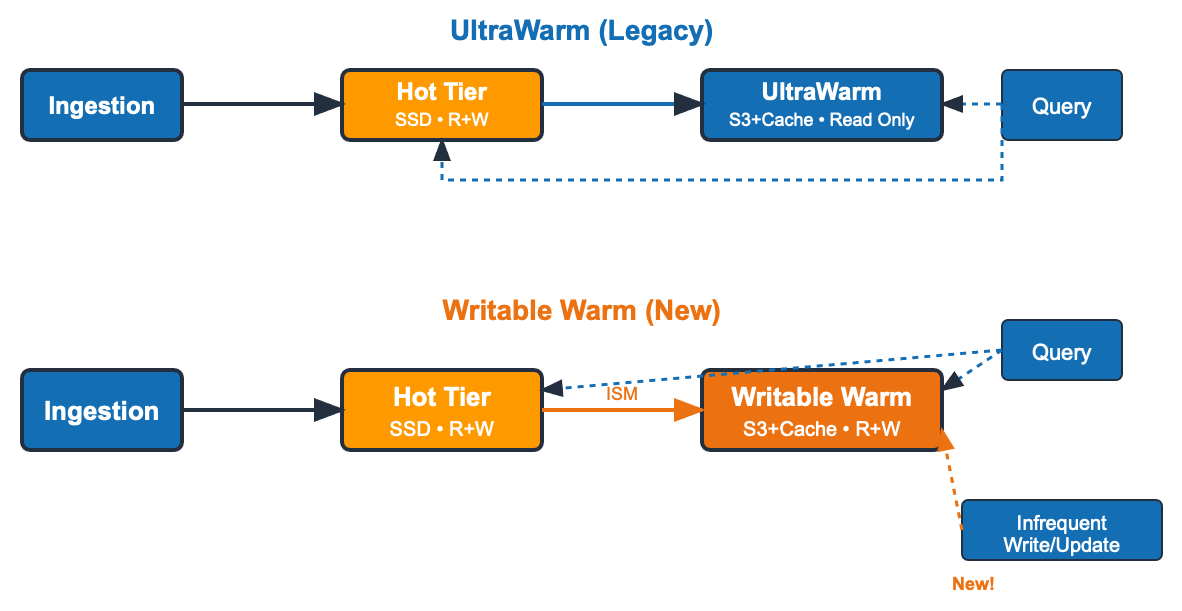
Diagram comparing UltraWarm and writable warm data flows. In the UltraWarm legacy flow, data is ingested into the hot tier, migrated to read-only UltraWarm, and any update requires a round trip back to hot. In the writable warm flow, indices transition from hot to writable warm, which accepts reads and writes directly without migrating back to hot.

UltraWarm (legacy) data flow: Data is ingested into the hot tier (SSD, read and write). Index State Management (ISM) policies migrate indices to UltraWarm (Amazon S3-backed, read-only). Any update requires migrating the index back to hot (dashed arrow), writing, then migrating back.

Writable warm (new) data flow: Same ingestion path through hot, with ISM transitioning indices to writable warm. The key difference is that writable warm supports both reads and writes. Late-arriving updates go directly to warm, with no migration back to hot. Because both tiers use Amazon S3 as durable storage through OpenSearch Optimized instances, transitions are lightweight shard relocations, not resource-intensive migrations.

The benefits: cost, operations, and flexibility

Writable warm delivers advantages in three areas: cost, operational simplicity, and flexibility.

Cost

Unlike UltraWarm, which only offers on-demand pricing, OI2 instances support Reserved Instance (RI) pricing, a commitment-based discount model. By committing to a 1-year or 3-year Reserved Instance, you can save 31–52 percent compared to UltraWarm nodes. This makes writable warm significantly more cost-effective for predictable, long-running workloads. The newly introduced Database savings plan for OpenSearch Service provides savings of around 22 percent over UltraWarm instances. Both tiers use Amazon S3 for durable storage, so node failure means only temporary unavailability, not data loss. For cost-sensitive workloads that can tolerate brief downtime during node recovery, you can configure zero replicas on warm indices to reduce costs further.

Real-world cost comparison

Consider a workload ingesting 2 TB/day with 210 days total retention, where updates can arrive at any point. With UltraWarm’s read-only constraint, you must keep data in hot for 30 days before migrating to warm. With writable warm, updates happen directly on warm, so hot retention drops to only 7 days.

At small scale, the hot tier reduction benefit is modest. Writable warm is still cost-effective if you need write capability on warm data, can commit to RI pricing, or value the operational simplicity of eliminating migration pipelines. For purely immutable data with short retention, UltraWarm on-demand might still be cheaper. Use the AWS Pricing Calculator to model your specific scenario.

The following table shows estimated monthly costs using on-demand and All Upfront Reserved Instance (AURI) pricing in the US East (N. Virginia) Region as of March 2026. For the latest pricing, see Amazon OpenSearch Service pricing on the AWS website.

Component Hot + UltraWarm (30d hot / 180d warm) Hot + writable warm (7d hot / 203d warm)
Hot data nodes $12,264 (21 × or2.2xlarge) $12,264 (21 × or2.2xlarge)
Hot EBS cost $10,212.84 (21 * 3986 GB) $2,636
Hot remote storage $2,008.28 $518
Warm data nodes $39,128 (20× ultrawarm1.large) $50,409 (15× oi2.8xlarge)
Amazon S3 storage $9,504 $1,070
Leader nodes $1,307 (3 × m8g.2xlarge) $1,307 (3 × m8g.2xlarge)
On-demand total $74,427 $69,297
1-year AURI $69,674 $43,918 (~36% less)
3-year AURI $67,367 $34,939 (~48% less)
Database savings plan $71,708 $55,406 (~22%)

Operations

Reclaim hot node capacity. Writable warm removes two common causes of hot node over-provisioning: reserving 35 percent of disk space for force merge operations, and maintaining extra capacity to temporarily move data back to hot for writes. You can run your hot tier at higher utilization, which reduces the number of hot nodes you need.

Simpler migrations. UltraWarm migrations are multi-step operations (force merge, snapshot, and shard relocation) that need careful scheduling during low-traffic windows, and they are limited to 10 queued at a time. Writable warm simplifies this to a lightweight shard relocation, with more straightforward ISM policies and no scheduling constraints.

Flexibility

UltraWarm offers only two instance sizes: ultrawarm1.medium (1.5 TiB) and ultrawarm1.large (20 TiB). Writable warm with OI2 instances offers a full range from oi2.large to oi2.16xlarge. Each size addresses up to 5× its local cache size, so you can right-size warm capacity precisely to your workload.

Search performance

We benchmarked search latency using the NYC Taxis workload, comparing writable warm (oi2.large) against UltraWarm nodes. All measurements are P90 latencies.

On the NYC_TAXIS benchmark, writable warm matched or beat UltraWarm on 6 of 7 query types at P90, including lightweight filters, ranges, sorts, and time-histogram aggregations. For most real-world search patterns, writable warm delivers comparable or better performance than UltraWarm, plus the ability to write directly to the tier.

Search performance: writable warm compared to UltraWarm

Task Writable warm node latency in ms UltraWarm latency in ms UltraWarm vs. writable warm diff %
NYC_TAXIS workload type ** ** ** ** ** **
default (P90) 21.287 23.857 12.07223
range (P90) 21.23 21.016 -1.00718
distance_amount_agg (P90) 5,069 3929.23 -22.48406
autohisto_agg (P90) 21.076 22.002 4.39348
date_histogram_agg (P90) 21.363 21.792 2.01031
desc_sort_tip_amount (P90) 23.224 23.797 2.46636
asc_sort_tip_amount (P90) 22.483 22.482 -0.00445

When to choose what

Should you switch from UltraWarm to writable warm? It depends on your workload.

Requirement Writable Warm UltraWarm
Write enabled ✓ Read-only
Reserved Instance pricing ✓ ✗
Instance size flexibility Wide range (large–8xlarge) 2 options only
Cold tier support ✗ ✓
Need for OpenSearch Optimized instance families ✗ ✓
Concurrent tier transitions ✓ ✗ (sequential)
Hot node impact during migration Minimal High (CPU/memory)

Clean up resources

If you created a test domain to evaluate writable warm storage, delete it to avoid ongoing charges. In the OpenSearch Service console, select your domain and choose Delete. This removes all nodes and stops Amazon S3 storage charges for that domain.

Summary

In this post, I showed you how writable warm storage eliminates the costly migration cycle that UltraWarm’s read-only limitation creates. You get up to 36 percent cost savings with 1-year Reserved Instances, faster search performance, and a simpler operational model. Writable warm also removes data transitions between tiers, and Reserved Instance pricing becomes available for warm storage for the first time.

Writable warm requires OpenSearch Service version 3.3 or later with OI2 instances. For domains needing cold tier support, earlier OpenSearch Service versions, or non-optimized instance families, UltraWarm remains the right choice.

Next steps: Start by analyzing your current hot and warm split. How many days of data do you keep in hot only to accommodate occasional updates? Use the AWS Pricing Calculator to model your potential savings, and enable writable warm on a test domain in minutes. At the time of this post, writable warm is supported on OpenSearch Service version 3.3. For step-by-step instructions, see Migrating to writable warm storage in the OpenSearch Service documentation.

Have you tried writable warm storage? I’d love to hear about your experience and any questions you have in the comments.


About the author

Bharav Patel

Bharav Patel

Bharav is a Specialist Solution Architect, Analytics at Amazon Web Services. He primarily works on Amazon OpenSearch Service and helps customers with key concepts and design principles of running OpenSearch workloads on the cloud. Bharav likes to explore new places and try out different cuisines.

Isolate email suppression per tenant with Amazon SES

Post Syndicated from Brett Ezell original https://aws.amazon.com/blogs/messaging-and-targeting/isolate-email-suppression-per-tenant-with-amazon-ses/

If you operate a multi-tenant email platform on Amazon Simple Email Service (Amazon SES), you know that managing email reputation across your tenants is a constant balancing act. Until now, all tenants in an Amazon SES account shared a single account-level suppression list. Suppose an email from Tenant 1 to Recipient A results in a hard bounce or a spam complaint. Amazon SES then places Recipient A’s email address on the account-level suppression list. As a result, none of your other tenants can send email to Recipient A. The block applies even when they have a valid, opted-in relationship with that recipient.

Tenant-level suppression lists solve this by allowing you to isolate bounce and complaint data per tenant, which eliminates cross-tenant contamination. With tenant-level suppression enabled, Amazon SES maintains a separate suppression list per tenant. Bounces and complaints affect only the sending tenant’s list. Other tenants can still attempt delivery to the same recipients.

In this post, you learn about the business problem this feature solves, how the new suppression precedence works, and how to implement tenant-level suppression for your multi-tenant email platform.

Quick reference

Item Detail
Feature Tenant-level suppression lists
Primary API operation PutTenantSuppressionAttributes
Scope options TENANT (isolated), ACCOUNT (shared, default)
Suppressed reasons BOUNCE, COMPLAINT, or both
Prerequisites Multi-tenancy enabled, production access
Key behavior Amazon SES evaluates exactly one suppression list per SendEmail call
Precedence order Configuration Set → Tenant → Account
Automatic recording Bounces → tenant list + global list. Complaints → tenant list only
Backward compatible Yes — opt-in per tenant, existing behavior unchanged

The cross-tenant suppression contamination problem in Amazon SES

Consider the following scenario. Imagine you run a SaaS marketing automation platform called “AnyCompany-SaaS.” You use Amazon SES multi-tenancy to send email on behalf of your customers (your tenants). For this example, consider Tenant A (a fast-growing fitness brand) and Tenant B (a conservative financial services company).

One day, Tenant A runs an aggressive, poorly targeted email campaign. Recipient A reports the email as spam, and that email address ([email protected]) gets added to your Amazon SES account-level suppression list to protect your sender reputation.

The problem? Tenant B has a perfectly valid, opted-in relationship with [email protected] and needs to send her a critical financial receipt. Before tenant-level suppression became available, AnyCompany-SaaS relied on the Amazon SES shared account-level suppression list. In this scenario, when Tenant B attempts to send email to [email protected], Amazon SES accepts the message but does not send it. The address is suppressed for every tenant in the account. Tenant B loses access to a valid recipient simply because of their neighbor’s poor email hygiene.

This is cross-tenant suppression contamination, and it creates several downstream problems:

  • Unfair deliverability outcomes — One tenant’s poor list hygiene affects all other tenants.
  • Increased support burden — Tenants ask “why is my email being suppressed?” and you have no clear answer.
  • Eroded trust — Your customers (the tenants) lose confidence in your platform’s email delivery capabilities.
  • Scaling challenges — The more tenants you add, the worse the contamination problem becomes.

Before today, the only workarounds were managing separate Amazon SES accounts per tenant (operationally expensive), or building custom suppression logic in your application layer (complex and error-prone). With Amazon SES tenant-level suppression lists, this shared-fate scenario is a thing of the past.

What is new: Tenant-level suppression lists

Each tenant in your account can now maintain its own isolated suppression list. When a hard bounce or complaint occurs for a tenant, Amazon SES records the suppressed address only on that tenant’s list. It does not add the address to other tenants’ lists.

Here is what this means in practice:

  • Isolation — Tenant A’s bounces and complaints affect only Tenant A’s suppression list.
  • Autonomy — Each tenant owns its own deliverability without impact from neighboring tenants.
  • Automatic management — Amazon SES automatically records entries based on hard bounces and complaints, and removes entries when recipients submit not-spam feedback.
  • Backward compatibility — Existing account-level suppression continues to work unchanged. Tenant-level suppression is opt-in per tenant.

Who benefits from tenant-level suppression?

This feature is designed for any organization that uses Amazon SES multi-tenancy to send email on behalf of multiple entities. Common use cases include:

  • SaaS platforms — Send transactional or marketing email for multiple customers, each with isolated suppression.
  • Marketing automation providers — Manage campaigns for different clients without cross-client contamination.
  • Enterprise multi-brand organizations — A corporation with multiple brands (for example, separate product lines or regional divisions) that need suppression isolation between brands.
  • Digital agencies — Manage email programs for dozens of clients under one Amazon SES account.
  • ISVs and resellers — Independent software vendors offering email capabilities as part of their platform.

When to use tenant-level vs. account-level suppression

Scenario Recommended scope Why
Single-tenant account (one brand, one sender) ACCOUNT No isolation needed — account-level works fine
Multi-tenant SaaS sending on behalf of customers TENANT Prevents cross-tenant contamination
Enterprise with multiple business units TENANT Each BU owns its deliverability independently
Per-workflow control within a single tenant Configuration set override Granular suppression at sub-tenant level
Migrating from separate Amazon SES accounts per tenant TENANT Consolidate into one account with isolation preserved

How Amazon SES tenant-level suppression precedence works

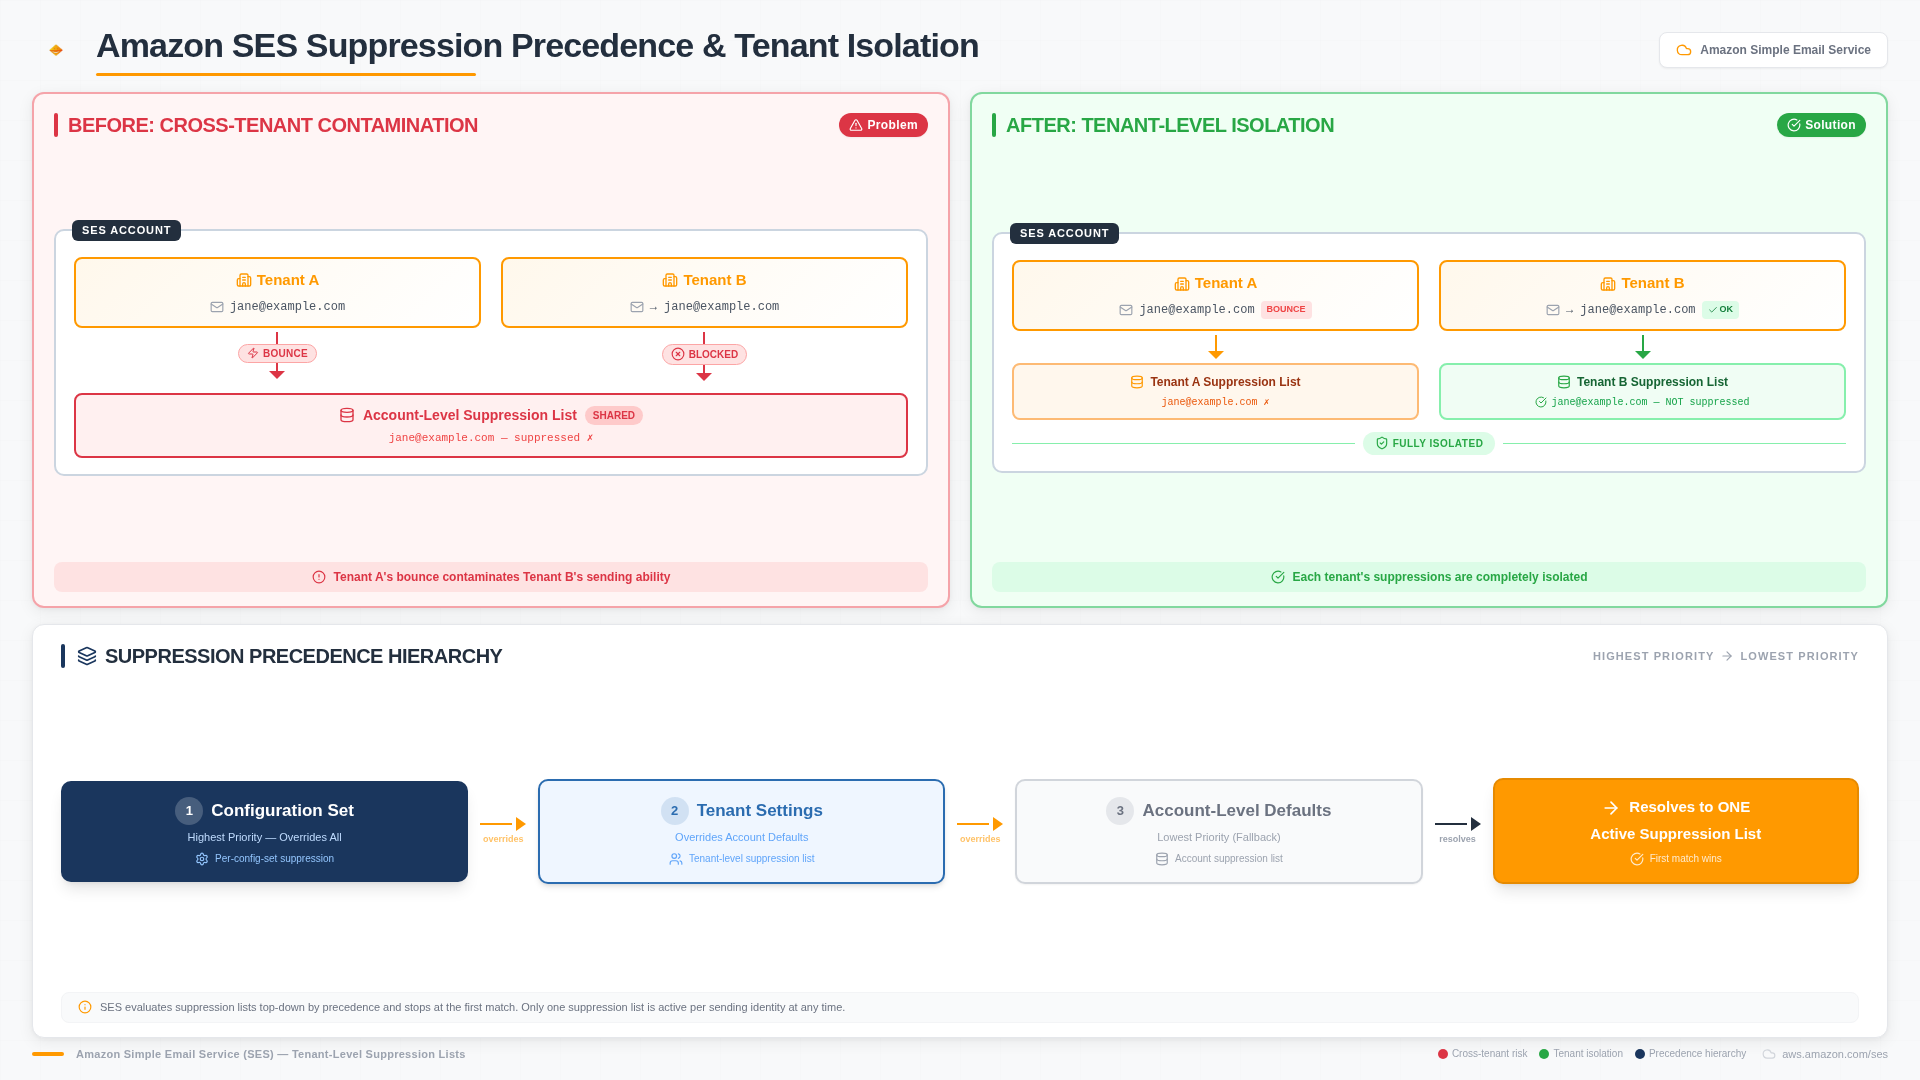
When you start mixing account-level lists, configuration sets, and tenant-level lists, it is important to understand how Amazon SES determines which list to check before sending an email. Amazon SES evaluates suppression rules in the following hierarchy (resolving to exactly one list).

Amazon SES suppression precedence resolving to one list: configuration set, then tenant, then account

Configuring suppression scope and suppressed reasons

Tenant-level suppression is controlled by two settings that you configure together:

  1. Suppression scope — Determines which suppression list Amazon SES checks at send time:
    • TENANT — Use the tenant’s own suppression list.
    • ACCOUNT — Use the account-level suppression list (this is the default).
  2. Suppressed reasons — Determines which events cause Amazon SES to automatically add addresses to the suppression list:
    • BOUNCE — Add addresses that produce hard bounces.
    • COMPLAINT — Add addresses that produce complaints.
    • Both BOUNCE and COMPLAINT — Add addresses for either event.

You configure both settings together using the PutTenantSuppressionAttributes API operation or by specifying SuppressionAttributes when creating a new tenant with CreateTenant.

Suppression precedence order

Behavior: Amazon SES evaluates exactly one suppression list per SendEmail call. The precedence is: Configuration Set > Tenant > Account. It does not check multiple lists in sequence.

Amazon SES resolves suppression settings using the following precedence order:

  1. Configuration set overrides (highest priority) — If the email is sent using a configuration set with a defined SuppressionOptions scope, Amazon SES uses that setting first.
  2. Tenant-level settings — If no configuration set override exists, and the email includes a TenantName, Amazon SES checks the isolated suppression list for that specific tenant.
  3. Account-level defaults (lowest priority) — If neither the configuration set nor the tenant specifies suppression settings, Amazon SES uses account-level defaults.

Important: An address that is on the account-level suppression list but not on the tenant’s list will not be suppressed when the scope is TENANT. Conversely, an address on the tenant’s list will not affect sends when the scope resolves to ACCOUNT.

Automatic suppression recording behavior

When the suppression scope is TENANT, Amazon SES automatically manages entries:

  • Hard bounces — Amazon SES adds the address to the tenant’s suppression list and the global suppression list. Amazon SES does not add the address to the account-level suppression list.
  • Complaints — Amazon SES adds the address to the tenant’s suppression list only.
  • Not-spam feedback — When a recipient marks a previously reported message as not spam, Amazon SES automatically removes COMPLAINT-reason entries from the tenant’s suppression list.

Prerequisites

Before implementing tenant-level suppression, make sure you have the following:

Required resources:

  1. An AWS account with Amazon SES configured.
  2. Multi-tenancy enabled with at least one tenant in your Amazon SES account.
  3. AWS Command Line Interface (AWS CLI) version 2 installed and configured with appropriate permissions.
  4. Production access (required for PutSuppressedDestination operations — sandbox accounts cannot manually add suppression entries).

Knowledge prerequisites: You should be familiar with Amazon SES account-level suppression concepts and multi-tenancy configuration.

Minimal example: Enable and send with tenant suppression

The following is the shortest path to enabling tenant-level suppression and sending an email that uses it:

# 1. Enable tenant suppression (bounces + complaints)
aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope TENANT \
    --suppressed-reasons BOUNCE COMPLAINT

# 2. Send email with tenant context — SES checks MyTenant's suppression list
aws sesv2 send-email \
    --from-email-address [email protected] \
    --destination '{"ToAddresses":["[email protected]"]}' \
    --content '{"Simple":{"Subject":{"Data":"Hello"},"Body":{"Text":{"Data":"Test message"}}}}' \
    --tenant-name MyTenant

# 3. Verify — list entries on the tenant's suppression list
aws sesv2 list-suppressed-destinations \
    --tenant-name MyTenant

Implementation walkthrough

Implementing tenant-level suppression requires configuring your tenants and updating your sending API calls. Here is how to get started using the AWS CLI.

Step 1: Enable tenant-level suppression for an existing tenant

First, you need to configure the suppression attributes for a specific tenant. In this example, you enable suppression for both bounces and complaints for MyTenant:

aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope TENANT \
    --suppressed-reasons BOUNCE COMPLAINT

A successful request returns an HTTP 200 response with no body. Verify the configuration:

aws sesv2 get-tenant --tenant-name MyTenant

The response includes the suppression configuration:

{
    "Tenant": {
        "TenantName": "MyTenant",
        "TenantId": "tn-abc123def456",
        "SendingStatus": "ENABLED",
        "SuppressionAttributes": {
            "SuppressionScope": "TENANT",
            "SuppressedReasons": ["BOUNCE", "COMPLAINT"]
        }
    }
}

You can also configure suppression for a single reason type:

# Suppress bounces only
aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope TENANT \
    --suppressed-reasons BOUNCE

# Suppress complaints only
aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope TENANT \
    --suppressed-reasons COMPLAINT

Step 2: Create a new tenant with suppression enabled

If you are creating a new tenant, you can enable suppression from the start using the CreateTenant API operation:

aws sesv2 create-tenant \
    --tenant-name MyNewTenant \
    --suppression-attributes '{"SuppressionScope":"TENANT","SuppressedReasons":["BOUNCE","COMPLAINT"]}'

The response contains the new tenant’s ID:

{
    "TenantId": "tn-xyz789ghi012"
}

Step 3: Verify suppression is working

After configuring a tenant, verify that suppression entries are being recorded correctly. You can list entries on a tenant’s suppression list:

aws sesv2 list-suppressed-destinations \
    --tenant-name MyTenant

To check if a specific address is on a tenant’s suppression list:

aws sesv2 get-suppressed-destination \
    --email-address [email protected] \
    --tenant-name MyTenant

Step 4: Send email with tenant context

When sending email, include the TenantName parameter so that Amazon SES evaluates the correct suppression list:

aws sesv2 send-email \
    --from-email-address [email protected] \
    --destination '{"ToAddresses":["[email protected]"]}' \
    --content '{"Simple":{"Subject":{"Data":"Hello"},"Body":{"Text":{"Data":"Test message"}}}}' \
    --tenant-name MyTenant

Step 5: Manually manage suppression entries

You can manually add or remove entries from a tenant’s suppression list. This is useful for pre-loading known bad addresses or removing addresses that have been re-validated.

To add an entry:

aws sesv2 put-suppressed-destination \
    --email-address [email protected] \
    --reason BOUNCE \
    --tenant-name MyTenant

To remove an entry:

aws sesv2 delete-suppressed-destination \
    --email-address [email protected] \
    --tenant-name MyTenant

Advanced: Configuration set overrides for per-workflow suppression control

For scenarios where you need per-workflow suppression control within a tenant, you can override tenant suppression settings at the configuration set level:

aws sesv2 create-configuration-set \
    --configuration-set-name my-config-set \
    --suppression-options '{"SuppressionScope":"TENANT","SuppressedReasons":["BOUNCE"]}'

You can also update an existing configuration set:

aws sesv2 put-configuration-set-suppression-options \
    --configuration-set-name my-config-set \
    --suppression-scope TENANT \
    --suppressed-reasons BOUNCE

Key considerations

Keep the following points in mind as you implement tenant-level suppression:

  • Sandbox restrictions — You cannot call PutSuppressedDestination while your account is in the Amazon SES sandbox. Request production access first. Note that this restriction only applies to manually adding entries. Automatic suppression from bounces and complaints works in sandbox mode.
  • Entries persist — Disabling tenant-level suppression does not delete existing entries from the tenant’s suppression list. If you re-enable tenant-level suppression later, those entries are still active.
  • Fail-close behavior — If the tenant suppression service is unavailable, Amazon SES suppresses the message rather than allowing it through.
  • The “no tenant” fallback — If you enable tenant-level suppression across your architecture but inadvertently miss updating a legacy microservice, any SendEmail call made without a TenantName parameter automatically falls back to evaluating your shared account-level suppression list.
  • Migration strategy — We recommend a phased migration. Start by configuring tenant-level suppression for new tenants or low-volume tenants first. Monitor their isolated lists using the ListSuppressedDestinations API before updating the SendEmail calls for your highest-volume legacy tenants.

Check the Amazon SES Developer Guide for the latest supported actions and service quotas.

Disabling tenant-level suppression

If you need to return a tenant to account-level suppression, you have two options:

Option 1: Explicitly set the scope to ACCOUNT:

aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant \
    --suppression-scope ACCOUNT \
    --suppressed-reasons BOUNCE COMPLAINT

Option 2: Clear all suppression settings:

aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant

When you omit both --suppression-scope and --suppressed-reasons, Amazon SES clears the tenant’s suppression settings, and the tenant falls back to account-level suppression behavior.

Cleaning up

If you followed along with this walkthrough and want to remove the resources you created, take the following steps:

Important: Disabling tenant-level suppression does not delete existing suppression entries. If you plan to re-enable this feature later, be aware that previously suppressed addresses remain on the tenant’s list.

  1. Clear tenant suppression settings (returns the tenant to account-level behavior):
aws sesv2 put-tenant-suppression-attributes \
    --tenant-name MyTenant
  1. If you created a test tenant, delete it:
aws sesv2 delete-tenant --tenant-name MyNewTenant
  1. If you created a configuration set for testing, delete it:
aws sesv2 delete-configuration-set \
    --configuration-set-name my-config-set

FAQ

Q: Does tenant-level suppression replace account-level suppression?

A: No. Account-level suppression continues to work unchanged. Tenant-level suppression is opt-in. You enable it per tenant by setting the suppression scope to TENANT. Tenants without this configuration continue using the account-level suppression list.

Q: What happens if I send an email without a TenantName parameter after enabling tenant-level suppression?

A: The email falls back to account-level suppression evaluation. Amazon SES only checks a tenant’s isolated suppression list when the SendEmail call includes the TenantName parameter and that tenant has SuppressionScope set to TENANT.

Q: Are existing suppression entries deleted when I disable tenant-level suppression for a tenant?

A: No. Entries persist on the tenant’s suppression list. If you re-enable tenant-level suppression later, those entries become active again. To remove entries, you must explicitly call DeleteSuppressedDestination for each address.

Q: Can a single email address appear on both the account-level and a tenant-level suppression list?

A: Yes. The same address can exist on multiple lists. However, Amazon SES only checks the list that the resolved scope points to. If the scope is TENANT, only the tenant’s list is evaluated. The account-level list is not consulted.

Q: Does tenant-level suppression work in the Amazon SES sandbox?

A: Automatic suppression recording (from bounces and complaints) works in sandbox mode. However, you cannot manually add entries using PutSuppressedDestination until you request production access.

Q: How do I migrate from separate Amazon SES accounts per tenant to a single account with tenant-level suppression?

A: We recommend a phased approach: (1) Create tenants in your consolidated account, (2) Enable tenant-level suppression for each, (3) Export suppression entries from the old accounts using ListSuppressedDestinations, (4) Import them into the new tenant lists using PutSuppressedDestination, (5) Update your sending logic to include TenantName in all SendEmail calls.

Q: What is the maximum number of entries on a tenant’s suppression list?

A: Tenant-level suppression lists follow the same limits as account-level suppression lists. Check the Amazon SES quotas page for current limits.

Conclusion

Tenant-level suppression lists give ISVs, SaaS platforms, and large enterprises the granular control they need to manage email deliverability fairly and effectively. No more shared suppression lists causing cross-tenant contamination, and no more tenants losing access to valid recipients because of a neighbor’s email hygiene problems. Each tenant now owns their reputation data independently.

To get started:

  1. Using tenant-level suppression lists in Amazon SES.
  2. PutTenantSuppressionAttributes API reference.
  3. Using the Amazon SES account-level suppression list.

You can also configure and manage tenant-level suppression directly from the Amazon SES console.

If you have questions or feedback, reach out to us on AWS re:Post or through your AWS account team. We look forward to hearing how you are using tenant-level suppression to improve your multi-tenant email platform.


About the author

S&P Global’s innovative disaster recovery strategy using Amazon FSx for NetApp ONTAP snapshots

Post Syndicated from Nishanth Charlakola original https://aws.amazon.com/blogs/architecture/sp-globals-innovative-disaster-recovery-strategy-using-amazon-fsx-for-netapp-ontap-snapshots/

This post is co-written by Nishanth Charlakola from S&P Global.

Organizations have a requirement to build high availability and disaster recovery (HA/DR) solutions for their complex SQL Server infrastructure to maintain data availability and integrity. With the rapid pace of cloud adoption, businesses across different industries have realized the value of a successful proof of concept (POC) for any technical project that migrates existing environments to the cloud. For companies of any size, it is important to set standards, minimize risks, and conduct business and technical validation while maintaining speed.

In this post, we explain how S&P Global Market Intelligence implemented an innovative disaster recovery solution for their Capital IQ platform using Amazon FSx for NetApp ONTAP. This solution enables immediate failover to read-only mode in a secondary region within 15 minutes, followed by full read-write recovery when needed. This approach achieves reduction in failover time while maintaining data consistency for global financial operations.

S&P Global Market Intelligence has been providing essential intelligence that unlocks opportunity, fosters growth, and accelerates progress for more than 160 years. The company offers Environmental, Social, and Governance (ESG) solutions, deep data, and insights on critical economic, market, and business factors.

Business challenge

S&P Global Market Intelligence must maintain uninterrupted access to information, even during regional outages. The Capital IQ platform supports global clients who rely on timely and accurate data for decision-making, with business requirements mandating strict Recovery Time Objectives (RTO) and Recovery Point Objectives (RPO).The primary business challenge was making sure that once the decision to fail over has been made, the DR read-only system becomes operational and accessible within 15 minutes. This rapid failover window makes sure you can continue accessing essential financial information with minimal disruption during failover events.

Key challenges addressed

  • Facilitating sub-15-minute access to critical financial data during regional service disruptions
  • Maintaining data consistency for financial reporting
  • Supporting system availability during production code releases
  • Optimizing cross-region data replication costs without compromising performance
  • Meeting regulatory requirements for business continuity in financial services
Solution overview

S&P Global’s DR strategy for the Capital IQ platform follows a two-pronged approach that balances immediate availability with complete recovery capabilities:
  1. Immediate failover to DR in read-only mode – using ONTAP snapshots and FlexClone technology for sub-15-minute recovery
  2. Conversion of DR system from read-only to read-write mode – following established geo-cluster design with SnapMirror replication

This approach helps you continue accessing essential financial data during disaster scenarios, even while the full recovery process is underway, facilitating business continuity without compromising data integrity.

Prerequisites

To implement this solution, you need the following:

Security and encryption

Amazon FSx for NetApp ONTAP supports encryption of data at rest and in transit, helping you meet security and compliance requirements. Data at rest is encrypted using AWS Key Management Service (AWS KMS) keys, and data in transit can be encrypted using SMB Kerberos encryption or NFS Kerberos. For SnapMirror replication, data transferred between file systems is encrypted in transit using AES-256-GCM encryption. For more information about security capabilities, see Security in Amazon FSx for NetApp ONTAP.

Architecture components

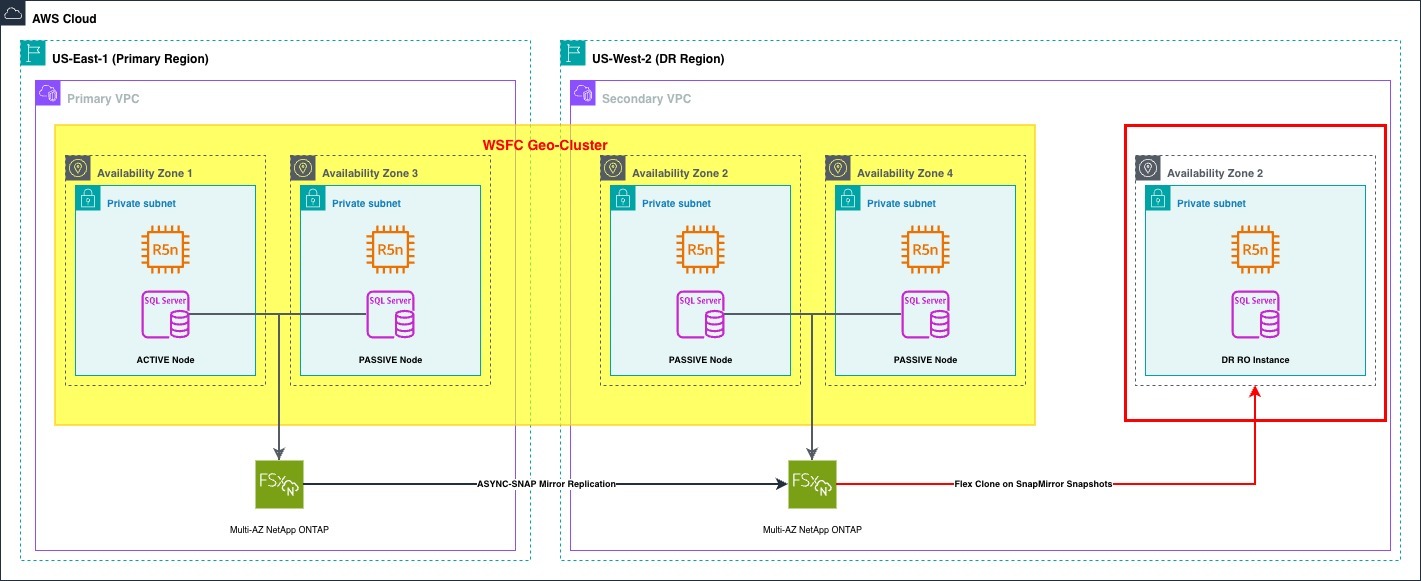
The solution architecture includes four key layers:

  • Compute layer: A four-node geo-distributed Windows Server Failover Cluster (WSFC) spanning two AWS Regions
  • Storage layer: Two Amazon FSx for NetApp ONTAP file systems, one in the primary region (US-East-1) and another in the DR region (US-West-2)
  • Data replication: SnapMirror replication from US-East-1 to US-West-2 with 15-minute intervals
  • Rapid recovery: FlexClone volumes created from existing SnapMirror snapshots in the DR region

AWS multi-region SQL Server high availability and disaster recovery architecture with WSFC Geo-Cluster spanning US-East-1 and US-West-2, using Amazon FSx for NetApp ONTAP with SnapMirror replication.

Figure 1. Cross-region disaster recovery architecture using Amazon FSx for NetApp ONTAP with SnapMirror replication and FlexClone-based rapid recovery.

Technical implementation

Cross-Region data replication

The Capital IQ team established SnapMirror replication between their production Amazon FSx for NetApp ONTAP file system in US-East-1 (N. Virginia) and their DR file system in US-West-2 (Oregon), making sure the DR region maintains a consistent copy of production data.The SnapMirror replication is configured with a 15-minute schedule between primary and DR Amazon FSx for NetApp ONTAP file systems. This frequent replication makes sure the DR region stays closely synchronized with production, minimizing potential data loss during failover events. The actual Recovery Point Objective (RPO) varies based on production environment activity. During lower activity periods, the RPO can be just a few minutes, while higher transaction volumes may result in a slightly increased RPO within the 15-minute window.

Using FlexClone for rapid recovery

A key element of S&P Global’s disaster recovery strategy is the use of NetApp FlexClone technology in conjunction with SnapMirror snapshots. A scheduled automation process refreshes the DR environment daily by identifying the most recent SnapMirror snapshot available in the DR region and creating a FlexClone volume from that point-in-time image. With this read-only DR instance pre-provisioned in advance, initiating failover is primarily an application cutover step — redirecting traffic to the ready instance in the DR region.This approach is highly efficient and non-intrusive. By using snapshots for FlexClone creation, the solution maintains the integrity of ongoing SnapMirror replication between production and DR environments. The FlexClone volume operates independently of the active SnapMirror relationship, meaning it does not interrupt or interfere with data replication processes. This separation allows continuous data protection and synchronization, even while the DR environment serves live read-only traffic.

FlexClone creation process

  1. Identify the latest SnapMirror snapshot in the DR region
  2. Create a FlexClone volume from this snapshot using the NetApp ONTAP CLI:

Note: The following example demonstrates a typical FlexClone creation command. Actual parameters should be adjusted for your environment.

volume clone create \-vserver dr-svm \-flexclone ciq_data_readonly \-parent-volume ciq_data_mirror \-parent-snapshot snapmirror.latest \-type RW

  1. Present the FlexClone volume and its LUNs to the read-only SQL Server instance in the DR region
  2. Direct application traffic to the read-only instance

Key advantages

  • Sub-15-minute recovery: FlexClone creation completes in under 2 minutes
  • Storage efficiency: FlexClones consume minimal additional storage as they share data blocks with the parent volume
  • Data consistency: The clone represents a point-in-time snapshot of production data
  • Operational isolation: The clone operates independently from ongoing SnapMirror replication

Full read-write recovery process

While read-only recovery provides immediate business continuity, transitioning to full read-write capability in the DR region follows these orchestrated steps:

  1. Stop SQL Server and freeze writes in the primary region
  2. Apply the final SnapMirror update to the DR region
  3. Break the SnapMirror relationship to make the DR volume read-write
  4. Reverse the replication direction (DR to primary)
  5. Fail over SQL Server resources to the DR nodes
  6. Resume normal operations in the DR region

Business benefits

This approach to disaster recovery has delivered significant benefits:

  • Enhanced business resilience: The solution maintained established RTO and RPO standards while transitioning to cloud infrastructure, successfully extending proven on-premises DR capabilities to the cloud.
  • Continuous access during outages: Clients experience minimal disruption during regional disaster scenarios. The pre-provisioned read-only instance means failover is a redirect, not a rebuild.
  • Resilience beyond disasters: Read-only instances also support application availability during production code releases extending the solution’s value beyond its original DR scope.
  • Lower infrastructure costs: FlexClone technology’s efficient data block sharing minimizes storage overhead in the DR region, reducing costs while maintaining comprehensive data protection.
  • Cloud-native without compromise: By moving from on-premises infrastructure to Amazon FSx for NetApp ONTAP, S&P Global gained cloud agility and elasticity while preserving the mature data management capabilities that financial services operations require.
  • Regulatory compliance: The solution meets stringent financial services requirements for business continuity and data availability.

Conclusion

S&P Global Market Intelligence’s implementation demonstrates that organizations can achieve both rapid disaster recovery and cost efficiency using Amazon FSx for NetApp ONTAP. By combining SnapMirror replication with FlexClone technology, they built a DR strategy that is faster, leaner, and more flexible than its on-premises predecessor while maintaining the reliability standards that 160 years of client trust demand.For financial services organizations navigating similar migrations, this approach offers a proven blueprint: replicate what works, modernize how it runs, and maintain the same level of data protection clients expect.

“Adopting Amazon FSx for NetApp ONTAP has helped us extend our proven disaster recovery strategy into the cloud. The ability to use native ONTAP snapshots and FlexClone technology on AWS enables us to deliver the same level of data protection and business continuity that our clients expect, without compromise. This solution bridges the gap between on-premises reliability and cloud agility.”

— Nishanth Charlakola, Director, S&P Global Market Intelligence

If you need guidance on implementing Amazon FSx for NetApp ONTAP or architecting disaster recovery solutions for financial services, contact your AWS account team.


About the authors 


Uncover new performance insights using Amazon detailed performance statistics on Windows

Post Syndicated from Xinze Zhang original https://aws.amazon.com/blogs/compute/uncover-new-performance-insights-using-amazon-detailed-performance-statistics-on-windows/

The primary storage solutions for EC2 Windows instances, Amazon EC2 Instance Store and Amazon Elastic Block Store (Amazon EBS) , now provide detailed performance statistics for real-time monitoring. Real-time monitoring enables you to gain visibility into key performance metrics, such as latency, throughput, and IOPS, allowing you to detect and address potential bottlenecks or issues proactively.

In this post, we explore how to use detailed performance statistics for both Amazon EBS and Instance Storage on Windows environments. These new metrics provide sub-minute granularity, offering real-time visibility into storage volume performance across both storage types. You can access these statistics directly from your Amazon EBS NVMe/Amazon Instance Storage NVMe device attached to the Amazon Elastic Compute Cloud (Amazon EC2) instance and use them to monitor I/O performance at the storage level. We also provide examples of how to use these statistics to quickly assess EBS volume/Storage health and identify performance bottlenecks, which improve both the reliability and performance of your applications. When creating or attaching EBS volumes, enable encryption at rest using AWS Key Management Service (AWS KMS) to protect your data. For more information, see Amazon EBS encryption in the Amazon EC2 User Guide.

Solution overview

Using the new Amazon EC2 Instance Store/Amazon Elastic Block Store (Amazon EBS) detailed performance statistics at the instance-level, this sample solution enhances observability and troubleshooting capabilities for latency-sensitive applications running on EC2 Nitro instances. We use the new nvme_amzn.exe tool to collect high-frequency statistics on I/O operations, latency, and queue length, enabling proactive troubleshooting.

As examples of how to use these granular metrics, this solution demonstrates how to validate the responsiveness of local storage and EBS volume, so that you can quickly identify any I/O interruptions. This solution helps you identify storage performance bottlenecks, which can be used to optimize the local storage and EC2 instance configurations for your workloads.

Prerequisites

This solution involves setting up an EC2 Nitro instance and an attached local storage to access detailed performance statistics for the local storage. This is a setup you likely already have if using Amazon EC2. To deploy the required components, you must complete the following steps:

  1. Launch an EC2 Nitro instance (or use an existing Nitro instance), and connect to it via Remote Desktop Protocol (RDP).
  2. Verify that your EC2 Windows instance includes AWS NVMe driver version 1.7.0 or later installed by following identify your driver type
  3. Identify the NVMe device associated with the local storage/EBS volume for which you want to query the stats. You can run the Get-Disk command in PowerShell to output all NVMe devices on the instance. For more information, see Map NVMe disks on Amazon EC2 Windows instance to volumes.

For this demonstration, we’ll monitor two storage volumes:

  • EBS volume (Disk 0): Serial Number vol01234567890abcdef_00000001.
  • Local storage (Disk 1): Serial Number AWSEXAMPLE1234567890_00000001.
  1. Ensure that nvme_amzn.exe is present in C:\ProgramData\Amazon\Tools by default.
  2. Use the nvme_amzn.exe tool, with administrator privileges, and pass the disk number as a parameter with different command. The returned output looks like the following.

Administrator: Windows PowerShell:

.\nvme_amzn.exe --help or nvme_amzn.exe /help

Users can see the EBS volumes devices mapping by default without passing the disk number as a parameter

.\nvme_amzn.exe

Users can view the specific device mapping by passing disk numbers or a single disk number as a parameter.

.\nvme_amzn.exe 0 1 2 3 4

Users can see the nvme controller details by using id-ctrl and pass the disk number as a parameter (JSON output can be retrieved by providing the --json or /json parameter to the tool)

# EBS volume
.\nvme_amzn.exe id-ctrl 0

# EC2 local storage
.\nvme_amzn.exe id-ctrl 1

.\nvme_amzn.exe id-ctrl 0 --json

Users can see the performance statistics for EBS/EC2 local storage volume by using stats and pass the disk number as a parameter (provide the --json or /json parameter to retrieve JSON output).

# EBS volume
.\nvme_amzn.exe stats 0
# Json format
.\nvme_amzn.exe stats 0 --json

# EC2 Local storage volume
.\nvme_amzn.exe stats 1
# Json format
.\nvme_amzn.exe stats 1 --json

In addition, for EC2 local storage volume, by providing the --details/-d option, you can see the histogram of 5 different IO bands: (0, 512 Byte], (512B, 4KiB], (4KiB, 8KiB], (8KiB, 32KiB], (32 KiB, MAX].

.\nvme_amzn.exe stats 0 --details

The following example shows NVMe log output with cumulative statistics. The statistics indicate read/write operations, bytes transferred, and time spent processing operations (in microseconds). They also show the number of microseconds in which the application attempted to exceed the Amazon EBS or Amazon EC2 Instance Local Storage IOPS/throughput limits

EBS volume:

EC2 local storage volume:

Also included in the following figures are read and write I/O latency histograms, with each row representing the total number of I/O operations completed so far within a specific bin of time (in microseconds).

These statistics are presented as cumulative counters up to the time at which the command is executed. The command can be run at the desired interval, for example, every 15 seconds, with each subsequent output reflecting the updated cumulative totals for the metrics. Calculating the difference in the statistics across the last two outputs allows you to derive insight into the instance storage profile over the given 15 second period.

Deriving insights from the Amazon Instance Storage/EBS volume detailed performance statistics

You have set up monitoring using these detailed performance statistics, now we can demonstrate the different ways you can use these statistics.

As mentioned in the preceding section, you can use the detailed statistics to view I/O latency histograms to observe the spread of I/O latency within the period. You can use the read/write operations and time spent statistics to calculate the average latency. Using the detailed statistics allows you to view the average latency at a sub-minute granularity.

Here are four examples for you to use the statistics to shed light on key performance metrics.

Scenario 1: Identifying unresponsive state of an EBS volume

In this scenario, we discuss how to use Amazon EBS detailed performance statistics to observe when an EBS volume isn’t responding to I/O operations. If you observe multiple intervals where your volume is unresponsive, then you can take actions, such as replacing the affected volume or stopping and restarting the instance to which the volume is attached. In most cases, when your volume becomes unresponsive, Amazon EBS automatically diagnoses and recovers your volume within a few minutes.

To identify if your volume is unresponsive, you can use the following steps to determine whether I/O disrupted on your volume:

  1. Identify the EBS volume’s NVMe device to troubleshoot
  2. Collect stats for the device at the desired intervals
  3. Compare the stats to check if the EBS volume is unresponsive

Step 1: Identify the EBS volume’s NVMe device to troubleshoot

1. Identify the NVMe device associated with the EBS volume on the instance by using the nvme_amzn.exe tool.

.\nvme_amzn.exe

Step 2: Collect stats for the device at the desired intervals

1. Collect the Amazon EBS detailed performance statistics directly from the device by using the nvme_amzn.exe tool:

# EBS volume disk0
.\nvme_amzn.exe stats 0

Step 3: Compare the stats to check if the EBS volume is unresponsive

1. From the output, consider the following three fields for this scenario: Total Read Ops, Total Write Ops, and Queue Length.

2. Issue the same ebsnvme command after a desired interval (for example: after 15 seconds), so that you can compare how Total Read/Write I/Os have progressed at the Amazon EBS level.

3. From the detailed performance statistics collected approximately 15 seconds apart, we make the following key observations

  • Total Read Ops increased from 1421153 to 1423480, indicating 2327 Read operations completed in the 15 second span.
  • Total Write Ops increased from 13835137 to 13846338, indicating 11201 Read operations completed in the 15 second span.
  • Queue Length stayed between 0 and 6, indicating that the application was issuing I/Os to the EBS volume. If you see a gradual increase in the Queue Length, then it would reflect a buildup in queued I/Os.

This shows that the EBS volume is still driving I/Os that it is receiving, which rules out the EBS volume as the source of observed degradation in application performance. If we had seen an increase in the Queue Length along with 0 Read/Write Ops processed during the period, then it would reflect an unresponsive EBS volume.

If you would like to validate your mechanisms of identifying unresponsive EBS volumes, refer to the Conducting chaos engineering experiments on Amazon EBS using AWS Fault Injection Service blog post, which walks through how to set up an AWS Fault Injection Service Pause I/O experiment.

Scenario 2: Identifying bottlenecks in storage performance on EBS

Amazon EBS detailed performance statistics can also be used to configure the appropriate performance characteristics for your EBS volume and EC2 instance based on the performance needs of your application. The EBS Volume Performance Exceeded and EC2 Instance EBS Performance Exceeded statistics indicate the duration for which your workload consistently attempted to drive IOPS or throughput that is greater than your volume or your instance’s provisioned performance in a given period. Exceeding either the volume’s or instance’s provisioned performance can result in elevated latency on your workload. For this scenario, consider the same application as the one used in scenario 1.

Complete the following steps to check if EBS volume performance is correctly provisioned:

1. Select the EBS volume’s NVMe device to check
2. Collect stats for the device at the desired intervals
3. Compare the stats to check if the EBS volume is exceeding provisioned performance

Step 1. Select the EBS volume’s NVMe device to check

1. This step is the same as Step 1 discussed previously in scenario 1.

Step 2. Collect stats for the device at the desired intervals

1. Similar to Step 2 discussed in scenario 1, access the detailed performance statistics across two points in time.

2. Consider the EBS Volume Performance Exceeded and EC2 Instance EBS Performance Exceeded statistics from the EBS NVMe device.

$DiskNumber = 0
$Interval = 15

while ($true) {
    Write-Host "=== $(Get-Date -Format 'yyyy-MM-dd HH:mm:ss') ===" -ForegroundColor Cyan; & "C:\ProgramData\Amazon\Tools\nvme_amzn.exe" stats $DiskNumber
    Write-Host ""
    Start-Sleep -Seconds $Interval
}

Step 3: Compare the stats to check if the EBS volume is exceeding provisioned performance

1. In the following example output, you can see the EBS Volume Performance Exceeded statistic increasing by 26813772 microseconds. This shows the workload running on EBS volume vol-EXAMPLEabcd1234 has attempted to drive more IOPS than provisioned on the underlying EBS volume, which can impact the volume’s I/O latency. We recommend that you increase the performance of your volume to make sure that you have sufficient provisioned performance for your application’s needs.

2. In the following example output, driving a different workload on the instance allows us to see that the volume has exceeded the provisioned IOPS performance at the attached EC2 instance level. In this case, up-sizing to a larger instance size can improve the performance of your application.

3. A synthetic load generator for Oracle called Silly Little Oracle Benchmark (SLOB) could also be used to simulate workloads on Oracle databases, while monitoring the Amazon EBS statistics to see which volume or instance is becoming the bottleneck.

It’s important to have the right instance and volume configurations to avoid performance bottlenecks to your application. Refer to the EBS volume types documentation for more information on the different EBS volume types, and the Amazon EBS-optimized documentation to understand how to select the optimal combination of EC2 instance and EBS volume suited for your application. These statistics are available at up to a one-second granularity, which allows you to effectively perform these checks in real-time and initiate volume modifications to optimize volume characteristics as needed.

Scenario 3: Identifying bottlenecks in storage performance on instance storage volume

Amazon Instance Storage detailed performance statistics can be used to configure the appropriate performance characteristics for your application. The “EC2 Instance local storage Performance Exceeded” statistics indicate the duration for which your workload consistently attempted to drive IOPS or throughput that is greater than your rate limit in a given period. Exceeding the throttle value can result in elevated latency on your workload.

For example, i3en.xlarge can support up to 85,000 read IOPS, 65,000 write IOPS, 634,765 KiB/S for read and 317,382 KiB/S for write. By using the detailed IO metrics, you can more efficiently determine if the instance meets your requirements.

Complete the following steps to check if the device meets your application needs:

  1. Select the instance storage device to check.
  2. Collect stats for the device at the desired intervals
  3. Compare the stats to check if the instance storage is exceeding the throttled value

Step 1. Select the Instance Storage NVMe device to check

Use the nvme_amzn tool and identify the NVMe device associated with the instance storage.

Step 2: Collect stats for the device at the desired intervals

$DiskNumber = 0
$Interval = 15

while ($true) {
    Write-Host "=== $(Get-Date -Format 'yyyy-MM-dd HH:mm:ss') ===" -ForegroundColor Cyan; & "C:\ProgramData\Amazon\Tools\nvme_amzn.exe" stats $DiskNumber
    Write-Host ""
    Start-Sleep -Seconds $Interval
}

Step 3: Compare the stats to check if the instance storage is exceeding throttle value

Take the following scenario as an example. At the very beginning, after the instance launch, both the IOPS and Throughput under “EC2 Instance local storage Performance Exceeded (us)” are 0s.

You start your applications and find that the application write does not meet your expectation. You can check the IO metrics afterwards. You see a lot of IO falls into the 1 ms to 2 ms range, which is unexpected.

By further checking the “EC2 Instance local storage Performance Exceeded (us)”. You found that the IO reached the allowed upper limit for up to 8 seconds, which indicates the i3en.xlarge would not meet your expectations. Select a larger instance size to address this.

It’s important to have the right instance size to avoid performance bottlenecks to your application. Refer to the ec2-instance-type-specifications documentation for more information on the different instance storage size to understand how to select the optimal instance size suited for your application. This tool helps you to effectively perform these checks in real-time.

Scenario 4: Identifying which block size caused the long latency on instance storage volume

You may have a mixed workload:

  • Data (either read or write) pattern with different block sizes like 4K and 128K.
  • Mixed read and write data pattern.

By using the --detail/-d switch from the NVMe CLI, you can identify the issue quickly and readjust the workload.

Example 1: High write latency from a workload

By further looking at the histogram of the block size range larger than 32 KiB, you can see that the larger IO caused high application latency, while other block sizes (like 8K) show no latency abnormality.

Example 2: Mixed read and write traffic

Some users will have a mix of read and write traffic. For example, some applications will do light read traffic (for example to read out some metadata) and heavy write. This may inadvertently impact the read latency. For example, an application is doing a read operation with a single IO of small block size. However, the user experiences high read latency. Examining the histogram breakdown, you could reasonably believe the heavy larger IO write may interfere with the read.

The detailed IO histogram for IO size larger than 512B but less than or equal to 4KB

The detailed IO histogram for IO size larger than 32 KiB

The user should consider smoothing out the write pattern to alleviate the read latency.

Cleaning up

If you created an EC2 instance and EBS volume for this exercise, then terminate and delete the appropriate instance and volumes to avoid future costs.

Conclusion

In this post, we presented a solution for accessing high-resolution performance statistics for Amazon EBS volumes and EC2 Instance Store at the instance level. These detailed metrics provide a real-time view into your underlying storage performance at sub-minute granularity, helping you to quickly root cause disruptions to your applications.

This approach also helps you identify performance bottlenecks caused by workloads exceeding your provisioned IOPS or throughput limits on Amazon EC2, EBS volumes, or EC2 Instance Store. Combined with Amazon CloudWatch metrics, which provide volume-level insights at one-minute granularity, these tools help give you the visibility you need to confidently diagnose and resolve storage-related performance issues.

Accelerating log analytics at scale with AWS Glue and Apache Iceberg materialized views

Post Syndicated from Shinu Tharol original https://aws.amazon.com/blogs/big-data/accelerating-log-analytics-at-scale-with-aws-glue-and-apache-iceberg-materialized-views/

Managing high-volume application logs at scale presents challenges from slow query performance and difficulty running complex aggregations to maintaining real-time analytics on streaming data. Apache Iceberg materialized views with AWS Glue, Amazon Data Firehose, and AWS Lambda address these challenges by accelerating log analytics through pre-computed query results.

In this post, you learn how to build an application log pipeline for production use with Amazon CloudWatch Logs, AWS Lambda, Amazon Data Firehose, AWS Glue, and Apache Iceberg materialized tables. You then use materialized views to accelerate query performance. This solution helps you achieve faster query response times on large-scale log data without requiring you to manage continuous data lake refresh.

Solution overview

This solution accelerates log analytics by pre-computing query results through Apache Iceberg materialized views. By querying pre-aggregated results instead of scanning raw log data for every request, you can help reduce query response times. For example, queries that previously took minutes scanning terabytes of raw data may return in seconds from the compact materialized view. Results update automatically as new logs arrive, helping you handle high-volume log streams while maintaining fast analytics performance.

Architecture overview

The architecture consists of AWS services working together to create a data pipeline:

  • Amazon CloudWatch Logs receives application logs and system events, then routes them to downstream targets using CloudWatch Logs subscription filters. CloudWatch Logs has a built-in retry mechanism. If the destination service returns a retryable error, CloudWatch Logs automatically retries delivery for up to 24 hours.
  • AWS Lambda serves as the transformation layer, parsing log messages, enriching data, and preparing records for storage.
  • Amazon Data Firehose buffers incoming data and handles the technical requirements of writing to Apache Iceberg tables (an open-source data table format), including batch optimization, schema validation, and automatic retry logic for failed writes.
  • Apache Iceberg tables stored in Amazon Simple Storage Service (Amazon S3) provide ACID transaction support, schema evolution capabilities, and efficient query performance. Materialized views are managed tables in the AWS Glue Data Catalog that store precomputed query results in Apache Iceberg format.
  • AWS Glue runs a one-time job during stack creation to provision the Iceberg database, base table, and materialized view structure in the Data Catalog. A second scheduled Glue job refreshes the materialized view by recomputing aggregations from the base table on a configurable interval helping downstream queries through Amazon Athena return up-to-date, pre-aggregated results without scanning raw data.

This architecture is designed to support automatic scaling, serverless infrastructure, error handling that routes failed records to Amazon S3 for analysis and replay, capture of failed Lambda invocations for automatic retry, and real-time monitoring through Amazon CloudWatch metrics.

Prerequisites

Before you deploy the solution, review the following prerequisites.

  • AWS account with necessary permissions to execute an AWS CloudFormation template, run AWS Glue jobs, run queries to verify Iceberg table data using Amazon Athena.
  • Basic familiarity with Boto3 to understand Python code. Foundational understanding of Apache Iceberg concepts.

Solution deployment

The following deployment steps guide you through implementing this solution in your AWS account.

Step 1: Deploy the AWS CloudFormation pipeline stack

You can deploy this solution using an AWS CloudFormation stack. The template handles creating Amazon S3 buckets, uploading AWS Glue and Lambda scripts, provisioning IAM roles, configuring the Firehose delivery stream, and running the Glue job to create the Iceberg database, base table, and materialized view.

Launch the stack in the AWS CloudFormation console. Review the parameters marked REQUIRED and adjust the toggle options (CreateScriptBucket, EnableLakeFormation, CreateSubscriptionLogGroup) based on your environment. Other parameters include preconfigured defaults that you should review for your environment. Choose the CloudFormation stack to deploy resources using the AWS CloudFormation console.

Pipeline stack required parameters view in the AWS CloudFormation console.

Additional pipeline stack required parameters in the AWS CloudFormation console.

Step 2: Test the end-to-end pipeline

Send sample log events matching the Iceberg table schema (for example, id, customer_name, amount, and order_date) to the CloudWatch log group. The subscription filter triggers the Lambda, which forwards records to Firehose for delivery into the Iceberg table.

git clone https://github.com/aws-samples/sample-log-analytics-iceberg-mv.git
cd sample-log-analytics-iceberg-mv
python3 scripts/send_test_logs.py
Terminal output showing the test log event script sending sample records to the CloudWatch log group

Execution of test events.

Verify data delivery and refresh the materialized view

Allow approximately 30 seconds (learn more in Buffer data for dynamic partitioning) for the Firehose buffer to flush. After the buffer flushes, run the following query in Amazon Athena to verify that data has been successfully delivered to the base table.

Query result using Amazon Athena.

Automated materialized view refresh

In this example, the AWS CloudFormation stack provisions a Glue job configured to run the materialized view (MV) refresh once daily at midnight UTC, meaning the MV reflects data up to the previous day. You can adjust the trigger’s cron schedule to match common MV refresh requirements such as hourly, every 15 minutes, or on demand.

The Glue job performs a full recomputation of the aggregations from the base Iceberg table and writes the results to the MV. Downstream consumers querying through Athena read from this pre-aggregated view, delivering faster performance. This is especially critical in real production scenarios where the base table contains millions of records and numerous columns. Computing aggregations directly from raw data at query time would degrade downstream application performance.

Job scheduled view in the AWS Glue console.

In a production environment, the base Iceberg table stores every individual order event, potentially millions of rows with dozens of columns growing daily. When dashboards or downstream applications need aggregated insights like daily revenue per customer or monthly order counts by region, querying the base table directly forces Athena to scan terabytes of raw data on every request. This results in slow response times and high costs at scale. The materialized view solves this by pre-computing these business-level aggregations once during the scheduled refresh, storing the results in a compact, purpose-built table with far fewer rows and columns. This means a dashboard query that would scan millions of raw records now reads from a pre-aggregated table, designed to reduce query response time. The base table remains your source of truth for granular, row-level lookups, while the materialized view serves as the performance layer for repeated analytical queries with embedded business logic.

Materialized View query result using Amazon Athena

Alternative: Amazon S3 Tables

This solution can also be implemented using Amazon S3 Tables, which provides a fully managed Apache Iceberg experience with native support for materialized views. In this post, we use the Glue-based approach to demonstrate the underlying mechanics and provide full flexibility to customize refresh logic for your specific requirements. To learn more, see Getting started with S3 Tables.

Clean up

To avoid incurring future charges, delete the resources you created as part of this exercise if you are not planning to use them further. Delete the stacks created in the previous steps, then empty and delete the Amazon S3 buckets.

Conclusion

This solution shows how to build a scalable application log data pipeline that delivers log events from Amazon CloudWatch Logs to Apache Iceberg tables using AWS Lambda and Amazon Data Firehose. This architecture uses fully managed AWS services to minimize operational overhead while providing high availability and consistent performance.

Key strengths include serverless infrastructure designed to support automatic scaling, error handling designed to route failed records to Amazon S3 for troubleshooting and replay, and analytics capabilities through Apache Iceberg’s ACID transactions and query performance optimizations. As you move this solution into production, we recommend that you implement data quality checks in Lambda and configure encryption at rest and in transit for your data. You can also establish data retention policies and explore partitioning strategies for better query performance.

You now have a log analytics pipeline built for production use that scales with your workload.

Additional resources


About the author

Shinu Tharol

Shinu Tharol

Shinu is a Technical Account Manager at AWS, delivering technical guidance and strategic support to enterprise customers. His expertise includes cloud operations, artificial intelligence, data analytics, and cloud cost optimization, enabling customers to maximize their AWS investments while maintaining operational excellence.

Serverless analytics pipelines using the Apache Spark engine in Amazon Athena

Post Syndicated from Avichay Marciano original https://aws.amazon.com/blogs/big-data/serverless-analytics-pipelines-using-the-apache-spark-engine-in-amazon-athena/

Building and maintaining clusters for data processing with Apache Spark has long been a pain point for organizations of all sizes. Traditional deployments require significant operational overhead and present multiple challenges that slow down time-to-insight and increase total cost of ownership. In this post, we will demonstrate three integration patterns that let data teams focus on analytics instead of infrastructure management.

Consider the typical experience of data teams working with self-managed Spark clusters:

  • Infrastructure complexity – Teams must manage Amazon Elastic Compute Cloud (Amazon EC2) instances, networking, security groups, and cluster configurations across development, staging, and production environments.
  • Cost unpredictability – Idle clusters continue consuming resources and generating bills, while automatic scaling policies often lag behind actual demand patterns.
  • Operational burden – DevOps teams spend significant time patching, monitoring, and troubleshooting cluster health issues.
  • Development friction – Data scientists and engineers must wait for cluster provisioning before they can begin exploratory analysis, slowing down iterative development cycles.
  • Interactive workload challenges – Managing interactive Spark workloads typically requires additional components, exposing specific ports, and complex network configurations.

These challenges become especially pronounced when organizations need to support multiple concurrent workloads: notebooks for data scientists, scheduled pipelines for data engineers, and ad hoc queries for analysts. The traditional approach encourages teams to choose between maintaining multiple clusters (expensive) or sharing resources (contentious) while maintaining fixed endpoint connectivity for interactive workloads (usually exposing JDBC ports for the Thrift protocol).

The Apache Spark engine in Amazon Athena addresses these operational challenges by providing a fully managed, serverless Spark execution environment. Built on Firecracker micro-VMs (AWS’s lightweight virtualization technology) and running the AWS-optimized Spark 3.5.6 engine with Spark Connect support, Athena with Apache Spark launches and scales in seconds, reducing costs for unpredictable workloads and infrastructure operational overhead.

Athena with Apache Spark is already integrated as a compute engine within Amazon SageMaker Unified Studio notebooks, providing rapid startup and scaling, making it ideal for ad hoc data exploration and transformations.

This post shows how developers, data engineers, and analysts can connect to a secure Spark Connect endpoint in Athena with Apache Spark. You can use your preferred tools, such as Jupyter notebooks, VS Code, or dbt with Apache Airflow, without managing cluster lifecycle or scaling.

Solution overview

We explore three integration patterns that demonstrate how the flexibility of Athena with Apache Spark can reduce operational overhead and accelerate innovation with on-demand resource readiness:

  • Pattern A: Interactive analysis with Jupyter notebooks – Data scientists connect notebooks directly to Athena with Apache Spark for exploratory analysis and feature engineering.
  • Pattern B: Local development with VS Code – Software engineers develop Spark applications in their preferred IDE (integrated development environment) while executing on serverless compute.
  • Pattern C: Scheduled pipelines with dbt + Apache Airflow – Data engineers run production transformation pipelines with proper orchestration and session lifecycle management.

The following diagram illustrates the high-level architecture for connecting to Athena with Apache Spark using Spark Connect.

Architecture for connecting to Athena with Apache Spark through a Spark Connect endpoint from Jupyter notebooks, VS Code, and dbt with Airflow

What’s new in the Apache Spark engine in Amazon Athena

In November 2025, the Apache Spark engine in Amazon Athena released a significant update with rapid session creation times and capabilities that weren’t possible with previous iterations:

  • Secure Spark Connect – Adds Spark Connect as a fully managed, authenticated, and authorized AWS endpoint for remote connectivity from Spark-compatible tools. For more information, see Spark Connect support.
  • Session-level cost attribution – Track costs per interactive session in AWS Cost Explorer or Cost and Usage Reports for granular chargeback and budgeting. For more information, see Session level cost attribution.
  • Advanced debugging capabilities – Live Spark UI and Spark History Server support for debugging workloads from both APIs and notebooks. For more information, see Accessing the Spark UI.
  • AWS Lake Formation integration – Access AWS Glue Data Catalog tables secured by AWS Lake Formation. For more information, see Using Lake Formation with Athena for Spark workgroups.

Prerequisites

To implement this solution, you need the following:

  • An AWS account with permissions for Amazon Athena, Amazon Simple Storage Service (Amazon S3), and AWS Glue.
  • An Athena with Apache Spark workgroup configured with the latest Spark 3.5.6 engine.
  • Python 3.9+ installed locally.
  • AWS credentials configured.

Note: This tutorial creates AWS resources that incur charges, including Athena sessions (charged per DPU-hour), Amazon S3 storage, and data transfer. Athena sessions are charged while active, even if idle within the timeout period. Follow the cleanup instructions at the end of this post to avoid ongoing charges.

Provisioning workflow overview

The workflow for using the Apache Spark engine in Amazon Athena with Spark Connect follows these steps:

  1. Create the session – Use the AWS API (start_session) to initialize a Spark session. The Spark driver is immediately ready to process requests (no JVM startup time).
  2. Get the Spark Connect endpoint – Retrieve the endpoint URL and authentication token using get_session_endpoint.
  3. Configure Your Tools – Set the SPARK_REMOTE environment variable or configure your tool with the Spark Connect URL.
  4. Run Processing Steps – Run your Spark code as you normally would, but in a fully serverless environment that scales automatically based on your needs.
  5. Monitor via Spark UI – Access the live Spark UI for debugging and performance monitoring using get_resource_dashboard.
  6. Terminate the session – Clean up resources when finished using terminate_session.

By default, the session is configured with autoscaling using Spark Dynamic Resource Allocation up to 60 workers and an idle timeout of 20 minutes. You can change the default configuration at the workgroup level when creating it (create_work_group API) or when creating the session (start_session API).

Pattern A: Interactive analysis with Jupyter notebooks

The Jupyter notebook integration provides an interactive environment for exploratory data analysis, feature engineering, and model preparation. Notebooks connect directly to Athena with Apache Spark sessions for rapid iteration without cluster management.

Set up the environment

Create and activate a Python virtual environment, then install the required dependencies and start JupyterLab:

python -m venv athena
source ./athena/bin/activate
pip install jupyterlab
pip install "pyspark[connect]==3.5.6"
pip install boto3
python -m jupyterlab

Create an Athena with Apache Spark workgroup

Before connecting, create an Athena with Apache Spark workgroup on the AWS Management Console:

  1. Navigate to Amazon Athena → Workgroups → Create workgroup.
  2. Select Apache Spark as the analytics engine.
  3. Choose the Spark 3.5.6 engine version.
  4. Configure the IAM role for the workgroup.
  5. Configure the Amazon S3 output location.

Note: If you used Athena with Apache Spark previously, you need to create a new workgroup to use the latest version with Spark Connect support.

Create a session and connect

In your Jupyter notebook, use boto3 to create a session and establish the Spark Connect connection:

import boto3

# Initialize the Athena client
client = boto3.client('athena', region_name='us-east-1') # Replace with your region

# Start a new Spark session
response=client.start_session(
    WorkGroup='your-workgroup-name',
    EngineConfiguration={}
)
session_id=response['SessionId']
print(f"Session created: {session_id}")

# Get the session endpoint and authentication token
response=client.get_session_endpoint(SessionId=session_id)
authtoken=response['AuthToken']
endpoint_url=response['EndpointUrl']

# Build the Spark Connect URL
endpoint_url=endpoint_url.replace("https", "sc") + ":443/;use_ssl=true;"
url_with_headers=f"{endpoint_url}x-aws-proxy-auth={authtoken}"

# Create the Spark session
from pyspark.sql import SparkSession
from pyspark.sql.functions import col, rand, sum, avg, count

spark = SparkSession.builder \
    .remote(url_with_headers) \
    .getOrCreate()

# Verify the connection
spark.sql("SELECT 1").show()

Run queries and observe automatic scaling

Generate a larger dataset to trigger executor scaling. You can monitor the scaling behavior through the Spark UI:

# Generate large dataset to trigger executor scaling
large_data = spark.range(0, 10000000, numPartitions=100)

# Heavy computation that will require more executors
result=large_data.select(
    col("id"),
    (col("id") * col("id")).alias("squared"),
    rand().alias("random")
).groupBy((col("id") % 1000).alias("group")).agg(
    sum("squared").alias("sum_squared"),
    avg("random").alias("avg_random"),
    count("*").alias("count")
).orderBy("group")

result.show()

Access the Spark UI

Each session comes with a secure URL serving the Spark UI, to monitor and debug applications:

import os

# Get account ID
sts=boto3.client("sts")
account_id=sts.get_caller_identity()["Account"]

# Build session ARN
partition=os.environ.get("AWS_PARTITION", "aws")
region="us-east-1"
workgroup="your-workgroup-name"
session_arn=f"arn:{partition}:athena:{region}:{account_id}:workgroup/{workgroup}/session/{session_id}"

# Get Spark UI URL
ui_response=client.get_resource_dashboard(ResourceARN=session_arn)
print(f"Spark UI: {ui_response['Url']}")

Pattern B: Local development with VS Code

VS Code integration lets you develop Spark applications locally in your preferred IDE while executing on Amazon Athena with Apache Spark compute. This pattern is ideal for building reusable libraries, testing transformations, and developing production-ready code.

Set up the environment

Create a virtual environment and install dependencies:

python -m venv athena-vscode
source ./athena-vscode/bin/activate
pip install "pyspark[connect]==3.5.6"
pip install boto3

Connect from VS Code

The workflow is identical to Pattern A. You start a session with boto3, build the Spark Connect URL, and create a SparkSession. The key difference is setting the SPARK_REMOTE environment variable, which allows SparkSession.builder.getOrCreate() to connect automatically:

import os
import boto3

# Start session and get endpoint (same as Pattern A)
client=boto3.client('athena', region_name='us-east-1')
response=client.start_session(WorkGroup='your-workgroup', EngineConfiguration={})
session_id=response['SessionId']
response=client.get_session_endpoint(SessionId=session_id)
endpoint_url=response['EndpointUrl'].replace("https", "sc") + ":443/;use_ssl=true;"
spark_remote=f"{endpoint_url}x-aws-proxy-auth={response['AuthToken']}"

# Set environment variable for automatic connection
os.environ["SPARK_REMOTE"]=spark_remote

# Now SparkSession connects automatically
from pyspark.sql import SparkSession
spark=SparkSession.builder.getOrCreate()

Note: The SPARK_REMOTE URL contains a short-lived authentication token that expires with the session. For production workloads, retrieve the token on demand using get_session_endpoint() rather than storing it persistently. Avoid logging or persisting this value.

This same pattern works with most Spark-compatible development environments. AI coding assistants like Claude Code, Cursor, and Kiro benefit particularly well from this approach. The ability to spin up a fresh Athena with Apache Spark session in seconds means developers can rapidly iterate on generated code and test transformations immediately. They can tear down sessions when done, without maintaining a persistent cluster between coding sessions.

Pattern C: Scheduled pipelines with dbt + Airflow

For production data pipelines, combining dbt (data build tool) with Apache Airflow orchestration provides a robust, version-controlled approach to managing complex transformation workflows. Athena with Apache Spark executes the dbt models with serverless compute, eliminating cluster management overhead.

Install dependencies

The key dependencies for dbt with Athena with Apache Spark must be installed in the correct order:

pip install pyspark[connect]==3.5.6 # Install first to ensure correct version
pip install dbt-spark[session]
pip install setuptools

Important: Install pyspark[connect]==3.5.6 first to make sure dbt uses the compatible PySpark version.

Configure dbt profile

Configure dbt to use Spark Connect with a session-based connection. Create a profiles.yml file:

The method: session configuration uses a local Spark session. When pyspark[connect]==3.5.6 is installed and the SPARK_REMOTE environment variable is set, dbt automatically connects through Spark Connect.

spark_connect_profile:
  target: dev
  outputs:
    dev:
      type: spark
      method: session
      schema: default
      database: default
      host: NA # Ignored by method=session
      user: dummy # Placeholder
      connect_timeout: 30
      connect_retries: 0

Create a dbt model

Create a dbt model that writes to Apache Iceberg format (models/bucketed_data.sql):

{{ config(
    materialized='table',
    file_format='iceberg',
    catalog='iceberg',
    location_root='s3://your-bucket/iceberg-tables'
) }}

WITH numbers AS (
    SELECT id
    FROM range(0, 100000)
),
buckets AS (
    SELECT
        id,
        id % 10 AS bucket,
        current_timestamp() AS created_at
    FROM numbers
)
SELECT * FROM buckets

Integrate with Airflow

For production deployments, integrate with Apache Airflow (or Amazon Managed Workflows for Apache Airflow (Amazon MWAA)) to orchestrate dbt runs with proper session lifecycle management.

The DAG follows this pattern:

  1. setup_athena_session – A PythonOperator that starts the session and pushes spark_remote_url to XCom.
  2. run_dbt – A BashOperator that sets SPARK_REMOTE from XCom and runs dbt.
  3. terminate_athena_session – A PythonOperator with trigger_rule=ALL_DONE to make sure cleanup runs even on failure.
from airflow import DAG
from airflow.operators.python import PythonOperator
from airflow.operators.bash import BashOperator
from airflow.utils.trigger_rule import TriggerRule
from datetime import datetime

with DAG(
    dag_id="athena_dbt_pipeline",
    schedule="@daily",
    catchup=False,
    start_date=datetime(2025, 1, 1),
) as dag:

    setup_session=PythonOperator(
        task_id="setup_athena_session",
        python_callable=setup_athena_session, # similar boto3 flow demonstrated earlier
    )

    run_dbt=BashOperator(
        task_id="run_dbt",
        bash_command="""
        export SPARK_REMOTE="{{ (ti.xcom_pull(task_ids='setup_athena_session') or {}).get('spark_remote_url', '') }}"
        source /path/to/dbt-env/bin/activate
        dbt run --project-dir . --profiles-dir .
        """
    )

    close_session=PythonOperator(
        task_id="terminate_athena_session",
        python_callable=terminate_athena_session,
        trigger_rule=TriggerRule.ALL_DONE,
    )

    setup_session >> run_dbt >> close_session

Security and best practices

When you connect to Athena with Apache Spark, follow these practices to protect your data and credentials.

Spark Connect security

Athena with Apache Spark uses Spark Connect to securely transmit queries and receive results. All communication is encrypted end-to-end using TLS 1.2+. Session tokens are short-lived and automatically rotated.

Recommendations:

  • Use IAM roles for authentication rather than long-lived credentials.
  • Session tokens have a limited lifetime, so refresh them for long-running operations.
  • Monitor Spark Connect activity in AWS CloudTrail for audit compliance.

IAM permissions

Implement least-privilege IAM policies. At minimum, the following permissions are required:

  • athena:StartSession, athena:TerminateSession, athena:GetSession, athena:GetSessionEndpoint, and athena:GetResourceDashboard on your workgroup.
  • Amazon S3 permissions for your data buckets.
  • AWS Glue Data Catalog permissions for your database and table access.

Clean up

To avoid ongoing charges, remove the resources created during this walkthrough:

  1. Terminate any active Athena sessions:
    aws athena terminate-session --session-id <your-session-id>

  2. Delete the Athena workgroup you created for this tutorial using the Amazon Athena console or the DeleteWorkGroup API.
  3. Remove Amazon S3 objects created during testing, including query results and Iceberg table data at your configured output location. Data written to Amazon S3 persists after session termination and continues to incur storage costs.
  4. Delete any IAM roles created specifically for this walkthrough.
  5. Remove any AWS Glue Data Catalog databases and tables created during testing.

Conclusion

The Apache Spark engine in Amazon Athena with Spark Connect support transforms how teams build and operate Spark workloads. By eliminating cluster management overhead and providing near-instant, serverless compute, data teams can focus on delivering insights rather than managing infrastructure.

The three patterns covered in this post demonstrate the flexibility of Athena with Apache Spark:

  • Pattern A (Jupyter notebooks) – Ideal for data scientists doing exploratory analysis and feature engineering.
  • Pattern B (VS Code) – Well-suited for software engineers building production-ready Spark applications.
  • Pattern C (dbt + Airflow) – Well-suited for data engineers running scheduled, version-controlled transformation pipelines.

With rapid session creation, automatic scaling, and pay-per-use pricing, Athena with Apache Spark provides a compelling alternative to self-managed Spark clusters.

Additional resources


About the authors

Avichay Marciano

Avichay Marciano

Avichay is a Sr. Analytics Solutions Architect at Amazon Web Services. He has over a decade of experience in building large-scale data platforms using Apache Spark, modern data lake architectures, and OpenSearch. He is passionate about data-intensive systems, analytics at scale, and it’s intersection with machine learning.

Vincent Gromakowski

Vincent Gromakowski

Vincent is an Analytics Specialist Solutions Architect at AWS where he enjoys solving customers’ analytics, NoSQL, and streaming challenges. He has a strong expertise on distributed data processing engines and resource orchestration platform.

Vova Nevski

Vova Nevski

Vova Nevski is a Senior Analytics Specialist Solutions Architect at AWS with more than 15 years of experience in the data and analytics domain. He partners with AWS customers to design and build solutions best suited to their unique needs.

Secure Amazon container workloads using container attribute-based rules in AWS Network Firewall

Post Syndicated from Amit Gaur original https://aws.amazon.com/blogs/security/secure-amazon-container-workloads-using-container-attribute-based-rules-in-aws-network-firewall/

Today, you can use AWS Network Firewall to protect traffic flowing to and from containerized applications on Amazon Elastic Kubernetes Service (Amazon EKS) and Amazon Elastic Container Service (Amazon ECS) clusters. If you run AI and machine learning (ML) workloads on Amazon EKS—such as model inference, RAG pipelines, or JupyterHub—your containerized workloads require the same firewall protections you enforce for traditional applications. However, traditional firewall rules rely on IP addresses, and pod IPs in Kubernetes change frequently as containers scale or restart. Writing and maintaining static firewall rules based on these ephemeral IPs, CIDRs, and subnets is difficult and error-prone, which can leave gaps in your security posture.

Kubernetes Network Policies offer basic traffic control at the namespace level, operating at layers 3 and 4. Depending on your security requirements, you might need additional capabilities beyond what network policies provide: Layer 7 inspection, FQDN-based filtering, and protection from threats detected by managed IDS/IPS rules. Visibility into which pod or service generates blocked traffic is equally important, so you can troubleshoot faster and meet audit requirements.

You can use container attribute-based rules for Network Firewall to define firewall rules for your containerized workloads on both Amazon EKS and Amazon ECS using native container attributes, rather than relying on ephemeral IP addresses. For Amazon EKS, these attributes include namespaces, pod names, cluster names, and labels. This reduces the need to maintain IP-based rules in dynamic container environments. While this capability supports both Amazon EKS and Amazon ECS, this post focuses on Amazon EKS. Your containerized workloads get the same Network Firewall capabilities you use today.

There is no additional charge for the feature itself, because it’s included in the base tier of Network Firewall.

How it works

When you create a container association and link it to your EKS cluster, Network Firewall automatically discovers and tracks the pods that match your defined attributes (namespace, labels, cluster name) and resolves them to their current IP addresses. As pods scale up or restart, the firewall dynamically updates the IP-to-attribute mapping in near real-time and no manual rule updates are required. This approach keeps your firewall rules accurate in dynamic environments while minimizing performance impact on the EKS cluster. In multi-cluster environments, this feature enables centralized cross-cluster traffic inspection for any traffic that passes through the firewall.

Container attribute-based rules also enrich firewall alert logs with container context. Alert logs now include a new metadata field with the container association name associated with the matched rule. This gives security teams the ability to trace blocked, allowed, or alerted traffic directly back to the originating workload. Network Firewall exports these enriched logs to Amazon CloudWatch Logs and Amazon Simple Storage Service (Amazon S3), from where you can forward them to the SIEM of your choice. To bind these attribute groups to running workloads, Network Firewall continuously watches your EKS cluster for pod lifecycle events (create and delete) across the namespaces covered by your container association definition. This definition is stored in a container association, keyed by attribute name and value.

When published, you reference these @ aliases in stateful Suricata rules. The following are some common patterns:

  • Pod group rules: Allow only payment-service pods to reach the external payment gateway over TLS:
    pass tls @ecommerce_pods any -> any 443 (msg:"allow ecommerce to payment gateway"; tls.sni; content:“checkip.amazonaws.com”; flow:to_server,established; sid:1; rev:1;)

  • Layer 7 application rules : Enforce block from all pods from reaching malicious destinations:
    drop tls @all-pods any -> $EXTERNAL_NET any (msg:"Block malicious sites"; aws_domain_category:malicious-sites; sid:10; rev:1;)

At packet evaluation time, Network Firewall expands each @ reference against the current catalog. When pods scale, restart, or move between nodes, the controller refreshes group membership, and the firewall picks up the new IPs, hence no rule edits or operator intervention is required. Each match—whether alert, pass, or drop—streams to the logging destination of your choice with container context. This gives your team a real-time, auditable view of policy effectiveness and a feedback loop for tuning rules and pod-group definitions over time.

Getting started

The Network Firewall container attribute-based rules for Amazon container workloads can be configured using the AWS Management Console for Amazon Virtual Private Cloud (Amazon VPC), AWS Command Line Interface (AWS CLI), or AWS SDK by creating a container association. This container association then can be used to create attribute-based Network Firewall rules.

Prerequisites

This walkthrough requires an existing Network Firewall configured to filter traffic through your Amazon VPC. If you haven’t set one up yet, see Getting started with AWS Network Firewall.

Step 1 – Create a container association:

  1. In the AWS VPC console, navigate to Network Firewall, select Container associations. Choose Create container association.
  2. Enter a Name and optional Description for this container association.
  3. Under Cluster configuration, select the Cluster type and select your EKS cluster from the Cluster drop down.
  4. For Attribute filters, configure the EKS attribute to identify which pods to associate:
    • Attribute key: Enter the attribute key defined in your EKS cluster (for example, namespace, pod, cluster, or custom label key).
    • Attribute value: Enter an attribute key value defined in your EKS cluster.
Figure 1: Create container association

Figure 1: Create container association

Step 2 – Create an attribute-based firewall rule:

  1. In the AWS VPC console, navigate to Network Firewall, then select Network Firewall rule groups.
  2. Select Create rule group.
  3. For Rule group type, select Stateful rule group.
  4. For Rule group format, select Suricata compatible rule string.
    Figure 2: Rule group selection

    Figure 2: Rule group selection

  5. For Rule evaluation order, select Strict order. Choose Next.
  6. Under Describe rule group, enter a Name, Description, and Capacity for the rule group. Choose Next.
    Figure 3: Describe rule group

    Figure 3: Describe rule group

  7. Under IP set references, enter a variable name and from the resource ID drop-down, select the container association created in step 1.
  8. Under Suricata compatible rule string, enter your Suricata rule string. The following is a sample string used for this post:
    pass tls @ecommerce_pods any -> any any (msg:"allow ecommerce to payment gateway"; flow:to_server; tls.sni; dotprefix; content:".checkip.amazonaws.com"; endswith; nocase; alert; sid:101; rev:1;)
    
    reject tls @ecommerce_pods any -> any 443 (msg:"block ecommerce pods to external ecommerce website"; flow:to_server; tls.sni; dotprefix; content:".amazon.com"; endswith; nocase; alert; sid:104; rev:1;)

    Figure 4: Configure rules

    Figure 4: Configure rules

  9. Choose Next.
  10. Enter the details if required on the next options. For this post, we’re using the default values.
  11. On the review and create page, choose Create rule group.

Tests and results

To verify these rules are working as expected, test using the curl command on a pod in the ecommerce namespace. A curl request to www.amazon.comshould fail, because action=rejectis defined in the Suricata rule string. Similarly, a request to the payment gateway URL should succeed, because action=passis defined in the Suricata rule string.

Test 1 – Allowed traffic:

kubectl exec -n ecommerce deployment/payment-service -- curl -sk --max-time 5 -w "\nHTTP_CODE:%{http_code}\n" https://checkip.amazonaws.com/

HTTP_CODE:200

Test 2 – Blocked traffic:

kubectl exec -n ecommerce deployment/payment-service -- curl -sk --max-time 5 https://www.amazon.com 2>&1

curl: (35) Recv failure: Connection reset by peer
command terminated with exit code 35

Container association can also be used in a Standard stateful rules format.

Considerations

There are several important considerations when adopting this feature.

  1. Source NAT (SNAT) must be disabled so that the Network Firewall can see pod IP addresses. If SNAT remains enabled, only the node IP will be visible, preventing granular pod-level egress controls.
  2. This feature can’t enforce security on pod-to-pod traffic within the same node, because that traffic doesn’t traverse the Network Firewall endpoint. A separate solution is needed for this use case.
  3. Performance impact can vary based on rule complexity and traffic volume.

Conclusion

In this post, you learned how container attribute-based rules for AWS Network Firewall solve the challenge of securing dynamic containerized workloads. You explored how the feature maps Kubernetes attributes such as namespaces, pod names, cluster names, and labels to firewall rules, eliminating the need to track ephemeral IP addresses. You walked through how to create a container association to link your EKS cluster attributes to Network Firewall, and then how to reference that association using IP set references in Suricata compatible rule strings. This gives you granular traffic control of your Amazon EKS workloads with the same Network Firewall capabilities as traditional applications including layer 7 inspection, FQDN filtering, TLS decryption, and managed IDS/IPS rules along with enriched logging that traces traffic back to the originating workload.

If you have feedback about this post, submit comments in the Comments section below.


Amit Gaur

Amit Gaur

Amit, a Cloud Infrastructure Architect at AWS, brings his passion for technology and knowledge-sharing to the networking community. Specializing in network architecture design, he helps customers build highly scalable and resilient environments on AWS. Through technical guidance and architectural expertise, Amit enables customers to accelerate their cloud adoption journey while making sure their systems are built for scale and reliability.

Preetkumar Shah

Preetkumar Shah

Preetkumar is a Technical Account Manager at AWS, based in Atlanta, GA. He specializes in helping customers design and operate secure, scalable network architectures in the cloud. At AWS, he works with SMB customers and collaborates closely with service teams to proactively resolve complex challenges and ensure customers get the most from their AWS environment. Outside of work, his interests include spending time with family and going on trails.

Akash Kuman Sinha

Akash Kumar Sinha

Akash is a DevOps Consultant and GenAI Ambassador at AWS, where he helps customers transform their cloud operations through containerization and modern delivery practices. He specializes in container orchestration and DevOps automation, and is a regular speaker at AWS events across Europe. Outside of work, Akash is passionate about knowledge-sharing and exploring the intersection of generative AI and cloud-native innovation.

Amish Shah

Amish is a seasoned product leader with over 15 years of experience in developing innovative and scalable solutions for networking, security, and cloud use cases. He currently leads the AWS Network Firewall service, where he helps to develop security solutions that protect AWS workloads. Outside of work, Amish enjoys playing cricket and soccer, loves to travel, and has recently started collecting niche fragrances.

AI-powered performance recommendations for Amazon Redshift

Post Syndicated from Steve Phillips original https://aws.amazon.com/blogs/big-data/ai-powered-performance-recommendations-for-amazon-redshift/

Data platform teams running Amazon Redshift collect performance telemetry across system views like SYS_QUERY_HISTORY, SVV_TABLE_INFO, and SVV_ALTER_TABLE_RECOMMENDATIONS, plus Amazon CloudWatch metrics for capacity, query execution, and storage. The challenge is interpretation. Correlating a spike in QueryRuntimeBreakdown commit time with hundreds of small INSERT statements, or connecting high disk spill with undersized compute, takes deep expertise and hours of manual analysis.

In this post, you learn how to build an AI-powered solution that collects the telemetry, pre-computes performance signals, correlates them with CloudWatch, and uses Amazon Bedrock to generate prioritized recommendations. The source code is in the accompanying GitHub repository: sample-ai-performance-advisor-for-amazon-redshift.

The signal-based design is what makes this solution produce precise recommendations rather than generic advice. Instead of dumping raw system view output into the large language model (LLM) prompt, the collector pre-computes boolean and threshold-based findings, pairs them with CloudWatch correlations, and hands the model a structured context. The model then cross-references specific query IDs, table names, and metric values in its output.

Solution overview

Two AWS Lambda functions run on a 24-hour Amazon EventBridge schedule:

  • The collector Lambda runs 13 diagnostic SQL queries against Amazon Redshift Serverless and reads the workgroup’s Workload Management (WLM) configuration. It also collects CloudWatch metrics across capacity, query execution, WLM, connections, and storage. From these inputs, it computes the performance signals. Finally, it writes a telemetry JSON file to Amazon Simple Storage Service (Amazon S3).
  • The analyzer Lambda reads the telemetry from Amazon S3, builds a structured prompt with inline CloudWatch-to-signal correlations. Using the correlations, the analyzer calls Amazon Bedrock (Anthropic Claude Sonnet 4.6), and writes the resulting recommendations JSON back to Amazon S3.
  • An Amazon Simple Notification Service (Amazon SNS) topic sends an email summary of the top recommendations to subscribers.
AWS architecture diagram showing an automated Redshift analysis pipeline within the AWS Cloud. Amazon EventBridge triggers a “Collector” AWS Lambda function, which interacts bidirectionally with AWS Secrets Manager, Amazon Redshift, and Amazon CloudWatch to gather data. The Collector passes results to an “Analyzer” AWS Lambda function, which exchanges data with Amazon Bedrock and reads/writes to Amazon S3. The Analyzer then publishes to Amazon Simple Notification Service (SNS), which delivers an email notification.

Figure 1 – Architecture diagram

Prerequisites

Before deploying the solution, make sure the following are in place.

  • An Amazon Redshift Serverless workgroup with a database and query history.
  • An Amazon Redshift database administrator user (superuser). The collector reads views that only a superuser can query (SVV_TABLE_INFO, SVV_ALTER_TABLE_RECOMMENDATIONS, SVV_MV_INFO, SYS_SERVERLESS_USAGE, SYS_AUTO_TABLE_OPTIMIZATION).
    Store the admin credentials in AWS Secrets Manager and pass the secret ARN to the collector.
    Alternatively, have an existing superuser run ALTER USER "IAMR:redshift-performance-recommendations-role" CREATEUSER;
    once to grant the Lambda role superuser privileges.
  • Amazon Bedrock model access for the model of choice. For this solution, a us.anthropic.claude-* model is recommended for multi-region inference. The solution doesn’t depend on a single model.
  • The AWS Command Line Interface (AWS CLI) installed and configured, and a clone of the GitHub repository.

Create the supporting resources

You need an Amazon S3 bucket, an Amazon SNS topic, an AWS Secrets Manager secret, and an AWS Identity and Access Management (IAM) role before the Lambda functions can run.

Create the Amazon S3 bucket

The Amazon S3 bucket will host the output report.

  • Open the Amazon S3 console and choose Create bucket.
  • Enter a globally unique name (for example, amzn-s3-demo-bucket), keep the default settings, and choose Create bucket.

The collector writes telemetry JSON under the telemetry/ prefix and the analyzer writes recommendations under the recommendations/ prefix.

Create the Amazon SNS topic and subscription

Use Amazon SNS to generate notifications once reports are created.

  • Open the Amazon SNS console and choose Topics, Create topic.
  • Select Standard, and enter the name redshift-performance-recommendations.
  • Choose Create topic.
  • On the topic detail page, choose Create subscription.
  • Select Email as the protocol, enter your email address, and choose Create subscription.
  • Open the confirmation email from AWS Notifications and choose Confirm subscription.
Amazon SNS “Create topic” console page. The Type is set to Standard (selected over FIFO), and the Name field contains “redshift-performance-recommendations.” Annotation arrows highlight the Topics nav item, the Standard topic type, the entered name, and the “Create topic” button in the lower right. Optional sections for Encryption, Access policy, Delivery policy, Message delivery status logging, Tags, and Active tracing are collapsed below.

Figure 2 – Create SNS Topic

Store the admin credentials in AWS Secrets Manager

To avoid using hard-coded credentials, create an AWS Secrets Manager secret to connect to Amazon Redshift.

  • Open the AWS Secrets Manager console and choose Store a new secret.
  • Select Other type of secret, choose the Plaintext tab, and paste the following, replacing <ADMIN_PASSWORD> with the workgroup’s admin password:
    {"username":"admin","password":"<ADMIN_PASSWORD>"}

  • Choose Next, enter redshift-performance-admin as the secret name, then choose Next, Next, and Store.
  • Copy the secret Amazon Resource Name (ARN) from the secret detail page. You pass it to the collector in a later step.
AWS Secrets Manager “Store a new secret” page, Step 1: Choose secret type. “Other type of secret” is selected, and the Plaintext tab shows the key-value pair {“username”:“admin”,“password”:“”}. The encryption key is set to aws/secretsmanager. Annotation arrows highlight the secret type selection, the plaintext credentials, and the “Next” button in the lower right.

Figure 3 – Create secret

Create the IAM role and attach the policy

The repository includes a trust policy in iam/trust-policy.json (allowing lambda.amazonaws.com to assume the role) and the least-privilege permission policy in iam/lambda-role-policy.json. Replace the <ACCOUNT_ID>, <REGION>, <YOUR_BUCKET>, and SNS topic ARN placeholders in the permission policy with your values, then create the role in the AWS Management Console or with this AWS CLI command:
aws iam create-role --role-name redshift-performance-recommendations-role \
    --assume-role-policy-document file://iam/trust-policy.json

aws iam put-role-policy --role-name redshift-performance-recommendations-role \
    --policy-name redshift-performance-policy \
    --policy-document file://iam/lambda-role-policy.json

The permission policy grants the Amazon Redshift Data API, Amazon S3, Amazon SNS, Amazon Bedrock, AWS Lambda invoke, AWS Secrets Manager, and Amazon CloudWatch Logs permissions that both Lambda functions require.

Deploy the Lambda functions

The collector source is in lambda/collector.py and it loads the SQL files in sql/ at runtime. The deployment package must contain both.

Package the collector

Open a terminal or shell window and execute a command to copy the collector code, supporting SQL into a folder and archive.

mkdir -p build/collector/sql
cp lambda/collector.py build/collector/
cp sql/*.sql build/collector/sql/
(cd build/collector && zip -qr ../collector.zip .)

Create the collector function

Using the AWS Management Console, navigate to AWS Lambda.

  • Choose Create function.

    AWS Lambda “Create function” console page with the “Configure custom execution role” panel open on the right. “Author from scratch” is selected, the function name is “redshift-performance-collector,” and the runtime is Python 3.14. Under Additional settings, the “Custom execution role” toggle is enabled, and the execution role list is set to “redshift-performance-recommendations-role.” Annotation highlights mark the Author from scratch option, function name, runtime, custom execution role toggle, the selected role, the Save button, and the “Create function” button.

    Figure 4 – Create AWS Lambda function

  • Select Author from scratch, enter redshift-performance-collector as the name, and select Python 3.14.
  • Expand Custom settings, toggle Custom execution role, choose an existing role, select redshift-performance-recommendations-role, and choose Save.
  • On the function page, choose Upload from, .zip file, and upload build/collector.zip.
  • In Runtime settings, select Edit, and set the Handler to collector.lambda_handler.

    Lambda console for the “redshift-performance-collector” function, Code tab. The code editor shows collector.py — a Python file that runs diagnostic SQL queries against Amazon Redshift Serverless, collects CloudWatch metrics, writes telemetry to Amazon S3, and invokes the analyzer Lambda. The Runtime settings section below shows the Handler highlighted as “lambda_function.lambda_handler,” with an arrow pointing to the Edit button and the “Upload from .zip file” option highlighted.

    Figure 5 – Set AWS Lambda handler

  • Choose Configuration, Edit, set timeout to 5 minutes, and memory to 256 MB.

    Lambda console for “redshift-performance-collector,” Configuration tab with “General configuration” selected. The panel shows Memory 128 MB, Ephemeral storage 512 MB, and Timeout 0 min 3 sec, with SnapStart set to None. Annotation arrows point to the General configuration menu item and the Edit button.

    Figure 6 – Set AWS Lambda timeout and memory

  • Under Configuration, select Environment variables, and add the following keys:
    • WORKGROUP: your Amazon Redshift Serverless workgroup name.
    • NAMESPACE_NAME: the namespace the workgroup belongs to.
    • DATABASE: dev (or your target database).
    • BUCKET: the Amazon S3 bucket name you created earlier.
    • SECRET_ARN: the AWS Secrets Manager secret ARN you copied earlier.
    • ANALYZER_FN: redshift-performance-analyzer.

Package and create the analyzer

Repeat the same steps for the analyzer, using lambda/analyzer.py with a 15-minute timeout:

(cd lambda && zip -q ../build/analyzer.zip analyzer.py)

Use the Lambda console to create redshift-performance-analyzer with handler analyzer.lambda_handler, timeout 15 minutes, memory 256 MB, the same execution role, and these environment variables:

  • BUCKET: the same Amazon S3 bucket.
  • SNS_TOPIC: the SNS topic ARN.
  • MODEL_ID: us.anthropic.claude-sonnet-4-6.

The analyzer creates the Amazon Bedrock client with read_timeout=600 and max_tokens=16384 to handle large prompts and long responses. Anthropic Claude inference on a full telemetry payload typically takes 2–4 minutes.

How the signals and the prompt work

You don’t write any custom code for signal computation or prompt construction. Both computation and construction live in the repository.

The compute_signals() function in lambda/collector.py scans the telemetry for Boolean and threshold-based anti-patterns. At the table level, it looks for row skew, ghost rows, stale statistics, unsorted data, sub-optimal sort or distribution keys, and oversized VARCHAR columns. It also flags runtime and workload issues such as disk spill, small-insert bursts, high Data Definition Language (DDL) executions, and unoptimized COPY file size. Beyond that, it catches Amazon Redshift Spectrum queries that fail to prune partitions and data sharing materialized views doing full refresh. It also flags WLM configurations that lack Query Monitoring Rules (QMR), such as limits on blocks spilled to disk and query execution time. The full set of signals and thresholds is defined inline in the function. To tune a threshold or add a custom signal, edit this function and redeploy.

The build_prompt() function in lambda/analyzer.py constructs the Amazon Bedrock prompt in four sections. The first section lists the triggered signals. The second adds CloudWatch metrics, annotated with >> CORRELATION lines that pair each signal with its supporting metric. The third includes the filtered supporting data, limited to the table and query rows that triggered a signal. The fourth gives explicit instructions to return a pipe delimited text where every recommendation references specific table names, query IDs, and metric values. This structure is why the model produces targeted output rather than generic best-practice advice.

Schedule daily runs

Use the Amazon EventBridge console to trigger the collector every 24 hours.

  • Open the EventBridge console and choose Schedules under Scheduler, Create schedule.
  • Enter the name redshift-performance-daily for Schedule name, toggle Recurring schedule and Rate-based schedule.
  • Under Rate expression, enter 24 and select hours.
  • For Flexible time window, choose Off, and select Next.
    Amazon EventBridge Scheduler “Create schedule” page, Step 1: Specify schedule detail. The schedule name is “redshift-performance-daily.” Under Schedule pattern, “Recurring schedule” and “Rate-based schedule” are selected, with a rate expression of 24 hours, and the time zone set to (UTC-06:00) America/Denver. Annotation highlights mark the Schedules nav item, the recurring/rate-based selections, the rate expression, and the Next button.

    Figure 7 – Create Amazon EventBridge schedule


  • On the Select target page, choose AWS Lambda, select the redshift-performance-collector function, and choose Next.

    EventBridge Scheduler “Create schedule” page, Step 2: Select target. “Templated targets” is selected and the AWS Lambda “Invoke” target is chosen from the grid of target options. In the Invoke section, the Lambda function list is set to “redshift-performance-collector” with an empty JSON payload. Annotation highlights mark the Templated targets toggle, the AWS Lambda Invoke target, the selected function, and the Next button.

    Figure 8 – Select Amazon EventBridge schedule target

  • Accept the defaults for Settings and select Next. EventBridge automatically adds a resource-based permission on the Lambda function so the rule can invoke it.
  • Choose Create schedule.

Run it once and review the output

Invoke the collector manually to confirm the pipeline works end-to-end.

  • In the Lambda console, open the redshift-performance-collector function and choose Test. Create a test event named manual with the body {} and choose Test.

    Lambda console for “redshift-performance-collector,” Test tab. A new test event named “manual” is being configured with Invocation type set to Synchronous, event sharing set to Private, the “Hello World” template selected, and an empty {} Event JSON body. Annotation arrows point to the function in the left nav, the Synchronous option, the event name, the Event JSON field, and the Test button.

    Figure 9 – Test end-to-end workflow

  • The function completes in under a minute. Check the Monitor tab for the invocation log via the CloudWatch live logs link.
  • In the Amazon S3 console, open your bucket. Confirm that the telemetry/ prefix contains a JSON file with the current timestamp.
  • Within 2–4 minutes, the analyzer publishes a message to the SNS topic. Check the email address you subscribed for the summary with the top 10 recommendations. Confirm that the recommendations/ prefix in Amazon S3 contains the full JSON.

Each recommendation has a priority (critical, high, medium, low) and a category (query_optimization, table_design, capacity, wlm, maintenance, or ingestion). It also includes a signal_source that names the signals and CloudWatch metrics that triggered it, a plain-language explanation, a specific SQL or configuration action, and an expected impact estimate.

Email notification from AWS Notifications with the subject “Redshift performance: 3 critical, 5 high, 4 medium, 2 low (8 signals)” highlighted. The body is a plain-text “Amazon Redshift Performance Recommendations” report listing workgroup, namespace, database, analysis time, and 14 recommendations. Two critical items are shown for the game_events table: fixing extreme row-skew via DISTSTYLE ALL, and eliminating non-encoded columns with column compression, each with a category, source, explanation, SQL action, and expected impact.

Figure 10 – Sample analyzer emailed output

Best practices

  • Tune thresholds to your workload. The default thresholds in compute_signals() come from the Amazon Redshift operational review playbook. For high-velocity ingestion or small-cluster environments, consider lowering the small-insert threshold, widening the stale-statistics window, or adding custom signals for your own tables.
  • Keep the signal-to-metric correlations current. When you add a signal, also add a matching correlation in build_correlations(). The inline >> CORRELATION lines are what make the model connect an infrastructure metric to an application-level symptom.
  • Review recommendations before you act. The analyzer produces prioritized suggestions, but VACUUM, ANALYZE, and ALTER TABLE actions change table state. Read the explanation and action on each recommendation, validate the SQL against your schema, and run it during a maintenance window.

Cleaning up

To avoid ongoing charges, delete the resources you created for this solution:

  • The two AWS Lambda functions: redshift-performance-collector and redshift-performance-analyzer.
  • The Amazon EventBridge rule: redshift-performance-daily.
  • The Amazon SNS topic and its email subscription: redshift-performance-recommendations.
  • The Amazon S3 bucket, including the telemetry/ and recommendations/ objects.
  • The AWS Secrets Manager secret: redshift-performance-admin.
  • The IAM role and its inline policy: redshift-performance-recommendations-role.

Conclusion

You now have a daily performance review for Amazon Redshift Serverless that runs entirely on AWS Lambda, stores every run in Amazon S3, and delivers prioritized recommendations by email. The signal-based prompt pattern keeps the Amazon Bedrock cost low and the recommendations specific to your workload.

To learn more, see the following resources:


About the authors

Steve Phillips

Steve Phillips

Steve is a Principal Technical Account Manager and Analytics specialist at AWS in the North America region. Steve currently focuses on data warehouse architectural design, AI/ML data foundations, data lakes, data ingestion pipelines, and cloud distributed architectures.

Richard Raseley

Richard Raseley

Richard is a Senior Technical Account Manager in North America who works with Games customers. He is passionate about applying his background in automation, cloud computing, networking, and storage to help customers build AI solutions.

How to use the AWS Workload Credentials Provider for cross-account secret retrieval and prefetching secrets

Post Syndicated from Derik Wang original https://aws.amazon.com/blogs/security/how-to-use-the-aws-workload-credentials-provider-for-cross-account-secret-retrieval-and-prefetching-secrets/

If you manage secrets across multiple AWS accounts or need faster secret access for latency-sensitive applications, this post shows you how to meet those requirements using two new features of the AWS Workload Credentials Provider (provider). You will learn how to configure role chaining for cross-account secret retrieval and prefetching of secrets to reduce cold-start latency.

By using role chaining, you can access secrets across AWS accounts through a single provider instance by assuming AWS Identity and Access Management (IAM) roles. Prefetching populates the provider’s in-memory cache with secrets at startup so your application can retrieve secrets without waiting for the first request to trigger a network call at runtime.

What is the AWS Workload Credentials Provider?

AWS Secrets Manager stores and rotates credentials, API keys, and other secrets. The AWS Workload Credentials Provider is a client-side HTTP service that retrieves and caches secrets locally. This reduces latency, improves availability during transient failures, and lowers costs. It supports post-quantum TLS by default, requires no language-specific SDK, and works across Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), and AWS Lambda. For more details, see the Workload Credentials Provider documentation and GitHub repository.

Security considerations

The Server-Side Requst Forger (SSRF) token prevents unauthorized processes from accessing the provider’s HTTP endpoint. Only applications that can read the token file can retrieve secrets through the provider.

Any identity that can access the provider’s endpoint and SSRF token can retrieve secrets through role chaining. This means users with compute environment access can retrieve cross-account secrets when role assumption is configured. Scope the target role’s permissions to only the secrets required by following the principle of least privilege.

For prefetching, secrets are loaded into the provider’s in-memory cache at startup. Any process that can reach the provider’s localhost endpoint and provide a valid SSRF token can retrieve prefetched secrets from the cache.

Cross-account secret retrieval with role chaining

Organizations might store secrets in a dedicated AWS account, or need to share one secret across applications in different accounts. Until now, cross-account retrieval through the provider required attaching resource-based policies directly to each secret. Some customers prefer IAM role assumption. Before this feature, you had to deploy multiple provider instances with different credentials or build custom credential-switching logic. The provider now supports both approaches: resource-based policies and IAM role assumption. While role assumption is especially useful for cross-account scenarios, it also helps within the same account when secrets are protected by different customer-managed KMS keys.

When you include the roleArn query parameter in a request, the provider uses AWS Security Token Service (AWS STS) AssumeRole to obtain temporary credentials for the specified role and retrieves the secret with those credentials. The provider creates and caches a separate client for each role ARN, so subsequent requests to the same role reuse the existing client. Each role client maintains its own independent cache.

Note: The source account runs the Workload Credentials Provider and your application. The target account contains the secret you want to retrieve. A single provider instance in the source account can assume roles in one or more target accounts.

Prerequisites

  • A Workload Credentials Provider built and installed in your environment (see the README for build instructions)
  • AWS credentials configured in your compute environment with permission to call sts:AssumeRole on the target role ARN
    • If you also retrieve secrets from the source account through the provider, the credentials need secretsmanager:GetSecretValue and secretsmanager:DescribeSecret permissions for those secrets
  • A secret in a target AWS account that you want to retrieve
  • An IAM role in the target account with a trust policy that allows the provider’s identity to assume it

To build the Workload Credentials Provider

The provider is written in Rust and compiles to a single executable. The following steps are for an RPM-based system such as Amazon Linux 2023:

  1. Install build dependencies:
    sudo yum -y groupinstall "Development Tools"

  2. Install Rust:
    curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh
    source "$HOME/.cargo/env"

  3. Clone the repository and build the provider (use the latest tag available):
    git clone --branch <git tag> https://github.com/aws/aws-workload-credentials-provider.git
    cd aws-workload-credentials-provider
    cargo build --release

The compiled binary is at target/release/aws-workload-credentials-provider.

To install the Workload Credentials Provider on Amazon EC2

After building the provider, install it as a system service on your EC2 instance and configure access to the SSRF token.

  1. After configuring your config.toml file (see Configuration options section), run the install script to deploy the provider as a systemd service and generate the SSRF token:
    cd aws_workload_credentials_provider_common/configuration
    sudo ./install --config config.toml

  2. Add your application user to the aws-wcp-token group. This grants your application permission to read the SSRF token file, which is required for all secret retrieval requests:
    sudo usermod -aG aws-wcp-token <APP_USER>

To install on Amazon ECS, Amazon EKS, or Lambda, see the installation instructions in the GitHub repository.

To verify the installation

  1. Check that the provider is running:
    curl -v -H \
        "X-Aws-Parameters-Secrets-Token: $(</var/run/awssmatoken)" \
        'http://localhost:2773/secretsmanager/get?secretId=<YOUR_SECRET_ID>'

  2. You’ll receive a JSON response with the secret value. If you see a connection refused error, check that the provider process is running. If you see a 401 or 403 error, verify the SSRF token file is readable and that the provider’s IAM credentials have secretsmanager:GetSecretValue and secretsmanager:DescribeSecret permissions.

Required permissions

The provider’s base IAM identity requires:

  • sts:AssumeRole on the target role ARN

The target role requires:

  • secretsmanager:GetSecretValue
  • secretsmanager:DescribeSecret

To configure the target account IAM role

Create an IAM role in the target account with a trust policy that allows the provider’s identity in the source account to assume it. Then attach a policy that grants access to the required secrets.

  1. Create an IAM role in the target account with a trust policy that allows the provider’s identity in the source account to assume it.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Principal": {
                    "AWS": "arn:aws:iam::111111111111:role/WCProviderRole"
                },
                "Action": "sts:AssumeRole"
            }
        ]
    }
    

  2. Attach a policy to this role that grants access to the secret:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "secretsmanager:GetSecretValue",
                "secretsmanager:DescribeSecret"
            ],
            "Resource": "arn:aws:secretsmanager:us-east-1:222222222222:secret:MyDatabaseSecret"
        }
    ]
}

To configure the source account IAM role

Before the provider can assume the role you created in the target account, grant it permission to call sts:AssumeRole. Attach the following policy to the provider’s IAM role in the source account:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": "sts:AssumeRole",
            "Resource": "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole"
        }
    ]
}

To retrieve the cross-account secret

Call the Workload Credentials Provider endpoint with the roleArn parameter. The following curl example shows how to retrieve a secret using a different IAM role:

curl -v -H "X-Aws-Parameters-Secrets-Token: $(</var/run/awssmatoken)" 'http://localhost:2773/secretsmanager/get?secretId=MyDatabaseSecret&roleArn=arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole'

The following Python example shows the same operation:

import requests

def get_secret_cross_account():
    role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole"
    url = f"http://localhost:2773/secretsmanager/get?secretId=MyDatabaseSecret&roleArn={role_arn}"

    with open('/var/run/awssmatoken') as fp:
        token = fp.read()

    headers = {
        "X-Aws-Parameters-Secrets-Token": token.strip()
    }

    response = requests.get(url, headers=headers)

    if response.status_code == 200:
        return response.text
    else:
        raise Exception(f"Status code {response.status_code} - {response.text}")

You can configure the maximum number of simultaneous assumed roles with the max_roles option in the provider’s TOML configuration file. The default is 20, and the range is 1–20.

Prefetching secrets at startup

By default, the Workload Credentials Provider populates its cache lazily—the first request for a secret triggers a network call to Secrets Manager. Prefetching reduces this cold-start latency by loading secrets at startup.

How prefetching works

You can configure prefetching by adding a [capabilities.secrets_manager.prefetch] section to the provider’s TOML configuration file. You can specify secrets to prefetch in two ways:

  • Explicit secrets – List specific secret IDs or ARNs using [[capabilities.secrets_manager.prefetch.secrets]] entries.
  • Tag-based discovery – Discover secrets by tag key using [[capabilities.secrets_manager.prefetch.filter_tags]] entries. The provider calls BatchGetSecretValue with tag key filters to find and cache all matching secrets.

You can use both methods together. Each entry optionally accepts a role_arn field for cross-account prefetching through role chaining.

Required permissions

The following permissions are required on the IAM role that performs the prefetch, depending on whether the secrets are in the source account or a target account.

  • secretsmanager:BatchGetSecretValue – Required on the source account role for source-account secrets, or on the target role for cross-account secrets
  • secretsmanager:ListSecrets – Required when using tag-based discovery (filter_tags), on whichever role is performing the discovery

Configuration options

You can tune prefetch behavior with the following options in the [capabilities.secrets_manager.prefetch] section of your TOML configuration file:

  • cache_buffer_ratio – The maximum fraction of the cache to fill per caching client during prefetch, in the range 0.1–1.0. The default is 0.8. For example, if your cache holds 100 secrets, a ratio of 0.8 prefetches up to 80, leaving room for 20 on-demand secrets to be cached.
  • max_jitter_seconds – The maximum random delay in seconds before starting the prefetch task, in the range 0–10. The default is 0 (no jitter). Use this to prevent fleet-wide synchronized API calls when deploying across many instances.

Example: Prefetch with explicit secrets

The following configuration prefetches two secrets at startup, one from the source account and one from a different account using role chaining:

[capabilities.secrets_manager.prefetch]
secrets = [
    { secret_id = "arn:aws:secretsmanager:us-east-1:111111111111:secret:MySecret-AbCdEf" },
    { secret_id = "cross-account-secret", role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole" }
]

Example: Prefetch with tag-based discovery

The following configuration discovers and caches all secrets tagged with the Environment key, and all secrets tagged with the Team key in a different account:

[capabilities.secrets_manager.prefetch]
filter_tags = [
    { key = "Environment" },
    { key = "Team", role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole" },
]

Example: Full configuration

The following example shows a complete provider configuration that combines both features:

[logging]
log_level = "info"

[capabilities.secrets_manager]
http_port = 2773
region = "us-east-1"

[capabilities.secrets_manager.cache]
ttl_seconds = 300

[capabilities.secrets_manager.prefetch]
cache_buffer_ratio = 0.6
max_jitter_seconds = 5
secrets = [
    { secret_id = "arn:aws:secretsmanager:us-east-1:111111111111:secret:MySecret-AbCdEf" },
    { secret_id = "arn:aws:secretsmanager:us-east-1:222222222222:secret:CrossAccount-AbCdEf", role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole" },
]
filter_tags = [
    { key = "Environment" },
    { key = "Team", role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole" },
]

Start the provider with your configuration file:

./aws-workload-credentials-provider sm start --config config.toml

Conclusion

This post showed you how to use role chaining for cross-account secret retrieval and prefetching to reduce cold-start latency. Role chaining simplifies multi-account architectures—a single provider instance can retrieve secrets across accounts using IAM role assumption. Prefetching reduces cold-start latency by populating the provider’s cache before your application makes its first request. Combined, these features let you run the Workload Credentials Provider across multiple accounts with faster secret access.

Further reading

Submit feedback in the comments below, or contact AWS Support with questions.


Derik Wang

Derik Wang

Derik is a Software Engineer on the AWS Secrets Manager team.

Paras Dhawan

Paras Dhawan

Paras is a Software Development Manager for AWS Secrets Manager, based in Seattle. Paras joined AWS in 2017 and has spent his career across AWS Identity, AWS Cryptography, and Credentials Distribution Systems. He is passionate to innovate, solve and simplify customer problems related to security, access, authorization and beyond.

Build an AI-powered real estate assistant on WhatsApp using Strands Agents SDK and AWS End User Messaging

Post Syndicated from Ruchikka Chaudhary original https://aws.amazon.com/blogs/messaging-and-targeting/build-an-ai-powered-real-estate-assistant-on-whatsapp-using-strands-agents-sdk-and-aws-end-user-messaging/

Most real estate websites collect form submissions and route them to sales teams who respond hours or days later. Customers who expect immediate answers often move on. This post shows how to close that gap with a WhatsApp assistant that responds instantly. We show you how to build a real estate assistant powered by AI that delivers property discovery, home loan pre-approval, and site visit booking entirely within WhatsApp. The solution uses the Strands Agents SDK to orchestrate specialized AI agents on Amazon Bedrock, with AWS End User Messaging Social for WhatsApp integration. The serverless backend runs on AWS Lambda and Amazon DynamoDB.

Prerequisites

You need an AWS account with permissions for AWS CloudFormation, Lambda, Amazon Simple Notification Service (Amazon SNS), Amazon Bedrock, and DynamoDB. You also need a WhatsApp Business account integrated with AWS End User Messaging. For instructions to locate your WhatsApp phone number ID, see View a phone number’s ID in AWS End User Messaging Social.

For more information about how to set up WhatsApp using AWS End User Messaging Social, refer to Automate workflows with WhatsApp using AWS End User Messaging Social.

AWS Serverless Application Model (AWS SAM) CLI is required to deploy the demo solution. For installation instructions, see the AWS SAM CLI installation guide.

Overview of solution

The architecture uses four AI agents built with the Strands Agents SDK. Each agent handles a specific task: identity verification, credit scoring, fraud detection, or property valuation. The agents use Strands SDK decorators to access external data sources. The agents run on Amazon Bedrock with the Nova Lite model and are deployed to AWS Lambda using the official Strands Agents Lambda Layer. AWS End User Messaging Social handles WhatsApp Business API integration, publishing incoming messages to Amazon SNS for routing. The webhook handler Lambda function processes these events and invokes the supervisor agent. The supervisor agent orchestrates the conversation flow, maintains session state in Amazon DynamoDB, and sends rich interactive messages back to customers on WhatsApp.

For this post, we use a demo landing page to simulate the “Enquire Now” button on a real estate website. In a production scenario, you can add this integration point to any existing website. The only requirement is a WhatsApp click-to-chat link that pre-fills the initial message with the property details.

The following diagram illustrates the solution architecture:

Solution architecture diagram: WhatsApp messages flow through AWS End User Messaging Social and Amazon SNS to a Lambda webhook handler and supervisor agent that orchestrates four Strands agents on Amazon Bedrock with session state in Amazon DynamoDB.

Strands Agents SDK — multi-agent pipeline

The Strands Agents SDK is an open source framework from AWS for building AI agents. Each agent gets a system prompt and tools. The agent then decides when to use those tools based on what the user asks.

This solution uses four specialized agents, each with its own tools:

  • Identity Agent – uses the verify_identity tool to validate the customer’s tax identification number.
  • Credit Scoring Agent – uses check_credit_score and get_loan_offers tools to assess creditworthiness and generate lending offers.
  • Fraud Detection Agent – uses check_fraud_risk to evaluate application risk.
  • Property Valuation Agent – uses validate_property to check regulatory registration and market value.

The following example shows how to define agents using the Strands @tool decorator pattern. Each tool is region-agnostic by design. You adapt the implementation for your local tax authority, credit bureau, and property registry.

from strands import Agent, tool
from strands.models.bedrock import BedrockModel

MODEL_ID = "amazon.nova-lite-v1:0"

def get_model():
    return BedrockModel(model_id=MODEL_ID, region_name="us-east-1")

@tool
def verify_identity(tax_id: str) -> dict:
    """Verify customer identity using their tax identification number.
    Adapt for your region: PAN (India), SSN (US), NIN (UK), TFN (Australia)."""
    # Call your regional tax authority API here
    return {"tax_id": tax_id, "valid": True,
            "holder_name": "Customer", "status": "Active"}

@tool
def check_credit_score(tax_id: str) -> dict:
    """Fetch customer credit score from a credit bureau.
    Adapt for your region: CIBIL (India), FICO (US), Experian (Global)."""
    # Call your regional credit bureau API here
    return {"credit_score": 782, "risk_category": "Low"}

@tool
def get_loan_offers(property_price: int, credit_score: int) -> dict:
    """Get mortgage offers from partner lending institutions.
    Adapt for your region's banks and lending regulations."""
    # Call your partner bank APIs here
    return {"offers": [...]}

@tool
def validate_property(name: str, registration_id: str, price: int) -> dict:
    """Validate property registration with the local regulatory authority.
    Adapt for your region: RERA (India), Land Registry (UK), MLS (US)."""
    # Call your regional property registry API here
    return {"registration_valid": True, "investment_rating": "good"}

You then orchestrate the agents in a pipeline:

def run_full_pipeline(tax_id, phone, project):
    # Agent 1: Identity Verification
    agent = Agent(
        model=get_model(),
        system_prompt="You are an Identity Verification Agent. "
                      "Use verify_identity to check the customer's tax ID.",
        tools=[verify_identity],
        callback_handler=None
    )
    identity = agent(f"Verify tax ID: {tax_id}")

    # Agent 2: Credit Scoring + Loan Offers
    agent = Agent(
        model=get_model(),
        system_prompt="You are a Credit Scoring Agent. "
                      "Use check_credit_score then get_loan_offers.",
        tools=[check_credit_score, get_loan_offers],
        callback_handler=None
    )
    credit = agent(f"Check credit for {tax_id}, "
                   f"get offers for price {project['price']}")

    # Agent 3: Fraud Detection
    # Agent 4: Property Valuation
    # ... similar pattern
    return consolidated_results

AWS End User Messaging Social

AWS End User Messaging Social handles WhatsApp Business API integration. Incoming messages arrive as events. Outgoing messages, including text, buttons, lists, and location cards, go through the SendWhatsAppMessage API.

Message routing with Amazon SNS

An SNS topic receives events from AWS End User Messaging Social whenever customers send WhatsApp messages.

Webhook handler – AWS Lambda

The webhook handler Lambda function parses the EUM Social event envelope, extracts the WhatsApp message payload, and routes it based on message type.

Supervisor agent – AWS Lambda with Strands Agents

The supervisor agent orchestrates the full conversation flow. It maintains session state in Amazon DynamoDB and sends rich WhatsApp messages back to the customer. When the customer submits their identification, the supervisor invokes the Strands agent pipeline, which runs four agents sequentially on Amazon Bedrock.

The supervisor sends interactive WhatsApp messages using the EUM Social API:

def send_list(self, to_phone, body, button_text, sections):
    payload = {
        "messaging_product": "whatsapp",
        "to": to_phone,
        "type": "interactive",
        "interactive": {
            "type": "list",
            "body": {"text": body},
            "action": {
                "button": button_text,
                "sections": sections
            }
        }
    }
    response = self.client.send_whatsapp_message(
        originationPhoneNumberId=self.phone_number_id,
        message=json.dumps(payload).encode('utf-8'),
        metaApiVersion='v21.0'
    )

Lambda Layer for Strands Agents

The Strands Agents SDK provides an official Lambda Layer that includes all required dependencies pre-built for the Lambda runtime.

Session state – Amazon DynamoDB

Two DynamoDB tables store conversation state. The sessions table tracks the full conversation state machine (INITIATED, AWAITING_PROJECT_SELECT, AWAITING_ACTION, AWAITING_ID, LOAN_APPROVED, VISIT_CONFIRMED), with a 30-minute TTL.

Conversation flow

The customer journey unfolds across four steps in WhatsApp.

Step 1: Property discovery

When the customer sends the initial message, the supervisor agent sends a welcome message followed by an interactive list picker showing properties grouped by developer. The list picker uses WhatsApp’s native interactive message format.

Step 2: Property detail with action buttons

When the customer selects a property, the supervisor sends a rich detail card with key highlights, regulatory registration, and three action buttons:

eum.send_buttons(phone, body, [
    {"id": "check_loan", "title": "Check Loan"},
    {"id": "book_visit", "title": "Book Site Visit"},
    {"id": "talk_sales", "title": "Talk to Sales"}
])

Step 3: Loan pre-approval with Strands Agents

When the customer chooses Check Loan and submits their tax identification number, the supervisor invokes the Strands agent pipeline. Four agents run sequentially on Amazon Bedrock, each using its specialized tools. The following log output shows the pipeline in action:

Running Strands agent pipeline for ID: ABCD****
Identity agent: True
Credit agent: score=782, offers=3
Fraud agent: low
Property agent: good

The customer receives a loan approval card with offers from multiple lending institutions, each with personalized interest rates based on the credit score returned by the credit agent. The full pipeline typically runs in under 10 seconds.

Step 4: Site visit booking

The customer selects a time slot from an interactive list picker and receives a confirmation with relationship manager details and a location card.

Demo implementation: India real estate market

This demo uses India-specific implementations: PAN validation for identity, CIBIL scores for credit (300-900 range), example bank offers with EMI in Rupees, RERA registration validation, and free cab pickup for site visits.

To adapt this solution for another region, you replace the tool implementations with calls to your local tax authority, credit bureau, lending institutions, and property registry. The agent architecture, WhatsApp integration, and conversation flow remain unchanged.

Deployment

To deploy the demo solution, run the following commands:

git clone https://github.com/aws-samples/sample-ai-powered-real-estate-agent.git
cd sample-ai-powered-real-estate-agent
./deploy.sh --env=demo \
    --phone-number-id <your-phone-number-id> \
    --business-number +14155552671 \
    --region us-east-1

After deployment, in the AWS End User Messaging Social console, route incoming messages for your phone number ID to the SNS topic demo-whatshome-incoming-messages created by the stack.

Test the solution

open demo/real-estate-landing.html

Select Enquire Now on any property card. WhatsApp opens at the configured business number with a prefilled message. Send the message and finish the loan pre-approval flow on WhatsApp.

Sample conversation

The following images show how a customer interacts with the real estate AI assistant.

WhatsApp screen showing the customer’s prefilled enquiry message and the AI assistant’s welcome reply with a list picker of available properties.

The customer lands on WhatsApp with a predefined message from the website, and the AI assistant greets them with a welcome message.

WhatsApp screen showing a property detail card with three action buttons: Check Loan, Book Site Visit, and Talk to Sales.

The customer selects the Check Loan option for one of the properties listed.


WhatsApp screen showing a loan approval card with offers from SBI, HDFC, and LIC Housing Finance, each with personalized interest rates.

The agents are invoked to verify the customer details and provide loan quotations.

WhatsApp screen showing a site visit confirmation with the assigned relationship manager’s details and a pinned location card.

The customer books a site visit after selecting a suitable time slot.

Clean up

To avoid ongoing charges, delete the resources you created during this walkthrough:

sam delete --stack-name whatshome-demo --region us-east-1

Deleting the CloudFormation stack removes the Lambda functions, DynamoDB tables, Amazon SNS topics, Amazon Simple Queue Service (Amazon SQS) queue, AWS Key Management Service (AWS KMS) key, and AWS Identity and Access Management (IAM) roles. If you deployed the demo landing page to Amazon Simple Storage Service (Amazon S3) and Amazon CloudFront, delete those resources separately.

Conclusion

You can combine the Strands Agents SDK, Amazon Bedrock, AWS End User Messaging Social, and Lambda to build an end-to-end WhatsApp assistant. The multi-agent architecture has specialized agents for identity verification, credit scoring, fraud detection, and property valuation. This decomposition shows how you can break complex business workflows into focused AI agents that collaborate to deliver instant results.

The same pattern works for banking loan applications, insurance claims, healthcare appointments, and ecommerce order tracking.

To get started, see the AWS End User Messaging Social documentation and the Strands Agents SDK on GitHub.


About the authors

Restrict AWS Management Console access to expected networks with sign-in resource-based policies and RCPs

Post Syndicated from Swara Gandhi original https://aws.amazon.com/blogs/security/restrict-aws-management-console-access-to-expected-networks-with-sign-in-resource-based-policies-and-rcps/

Amazon Web Services (AWS) recently announced support for resource-based policies and resource control policies (RCPs) for AWS Sign-In. By using resource-based policies and RCPs, you can restrict access to the AWS Management Console sign-in and aws login CLI sessions to requests from your expected networks, your on-premises data center networks, and your Amazon Virtual Private Cloud (Amazon VPC) VPCs.

Sign-in resource-based policies and RCPs support several security objectives: restricting console sign-in to corporate networks, limiting which principals can sign-in to the console, and applying consistent network perimeter controls across an entire AWS Organizations organization.

In this post, we walk through a common use case: a financial services company restricting console access to its corporate network for regulatory compliance. We show you how to implement this using a sign-in resource-based policy for a single account, verify the controls with AWS CloudTrail, and explain how these policies integrate with AWS Management Console Private Access and the broader AWS data perimeter framework.

Restricting console sign-in access to a corporate network

Consider a financial services company that requires access to AWS Management Console sign-in to originate from the corporate network. The company has the following requirements:

  • Users sign in to the console only from the corporate VPN, office network, or customer VPC.
  • Sign-in attempts from personal networks, public Wi-Fi, or other unexpected locations must be denied.
  • A designated principal should retain access from any network to prevent lockout.
  • All sign-in attempts (allowed and denied) must be logged to CloudTrail for compliance evidence.

In the steps that follow, we show you how to create a resource-based policy to enforce these requirements on a single account.

Prerequisites

  • AWS Command Line Interface (AWS CLI) installed and configured with the latest version.
  • Permission to manage Sign-in resource policies. Attach the AWS managed policy AWSSignInResourcePolicyManagement or grant permissions to the following actions to respective principals:
    • Manage resource permission statements: signin:PutResourcePermissionStatement, signin:DeleteResourcePermissionStatement, signin:ListResourcePermissionStatements, signin:GetResourcePolicy.
    • Manage console authorization: signin:PutConsoleAuthorizationConfiguration, signin:GetConsoleAuthorizationConfiguration, signin:DeleteConsoleAuthorizationConfiguration
  • Identified corporate network: IP CIDR range or VPC ID.
  • Designated principal Amazon Resource Name (ARN) to exclude, so it retains access if network conditions change.

Note: For the complete list of AWS Sign-In actions see Actions, resources, and condition keys for AWS Sign-In in the Service Authorization Reference.

Step 1: Create resource permission statements

Most resource-based policies require the author to input the full policy document (JSON statements). A Sign-in resource permission statement is different: you provide parameters, and AWS Sign-In generates the policy for you.

The following command provides your corporate IP range, your VPC, and an excluded principal as parameters. AWS Sign-In uses these parameters to generate a policy that restricts console sign-in to those networks, while letting the excluded principal sign in from any network. You control the parameter values, not the policy structure. You can review the generated policy at any time with the get-resource-policy command.

Note: Creating resource permission statements has no effect until console authorization is enabled in Step 2, so you can review the complete policy before it takes effect. Write operations must target us-east-1.

To create resource permission statements

1. Open your terminal and ensure you have the latest AWS CLI installed.
2. Run the following command, replacing the placeholder values <my-vpc>, <my-vpc-region>, <my-corporate-cidr>, and <excluded-IAM-principal-arn> with your specific configuration:

aws signin put-resource-permission-statement \
  --source-vpc <my-vpc> \
  --requested-region <my-vpc-region> \
  --source-ip <my-corporate-cidr> \
  --excluded-principal <excluded-IAM-principal-arn> \
  --region us-east-1

3. Verify the command succeeded by checking for a statementId in the output.

Example output:
{
“statementId":"b2HfHli9qCF1P4eGNll13CrZtusXlcPxxVBqz2aYLjlAcWtWQHP6Hg0"
}

4. Review the complete resource-based policy by running get-resource-policy command.

aws signin get-resource-policy

Example output:

{
  "signinResourceBasedPolicy": {
    "Version": "2012-10-17",
    "Statement": [
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:Authenticate"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"signin:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "NotIpAddress": {"aws:SourceIp": ["<my-corporate-cidr>"]},
          "StringEquals": {"aws:ResourceAccount": ["<account-id>"]},
          "StringNotEquals": {"aws:SourceVpc": ["<my-vpc>"]}
        }
      },
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:CreateOAuth2Token", "signin:AuthorizeOAuth2Access"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"aws:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "NotIpAddress": {"aws:SourceIp": ["<my-corporate-cidr>"]},
          "StringEquals": {"aws:ResourceAccount": ["<account-id>"]},
          "StringNotEquals": {"aws:SourceVpc": ["<my-vpc>"]}
        }
      },
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:Authenticate"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"signin:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "StringEquals": {"aws:SourceVpc": ["<my-vpc>"]},
          "StringNotEquals": {"aws:RequestedRegion": ["<my-vpc-region>"]}
        }
      },
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:CreateOAuth2Token", "signin:AuthorizeOAuth2Access"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"aws:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "StringEquals": {"aws:SourceVpc": ["<my-vpc>"]},
          "StringNotEquals": {"aws:RequestedRegion": ["<my-vpc-region>"]}
        }
      }
    ]
  }
}

The generated policy contains four statements, grouped into two pairs. The first pair restricts access by network source—it denies any principal making a request from outside your corporate IP range (<my-corporate-cidr>) or your VPC (<my-vpc>). The second pair restricts which AWS Region your VPC can target—it denies requests originating from <my-vpc> unless they are directed at <my-vpc-region>. This Region binding is necessary because VPC IDs are only unique within a single Region.

AWS Sign-In evaluates these policies in two phases: before authentication and after authentication. The post-authentication evaluation repeats each time the console session requests new credentials. Within each pair, one statement covers the pre-authentication phase and one covers the post-authentication phase.

The pre-authentication statement evaluates the signin:Authenticate action. Since the principal is not yet authenticated in this phase, the statement uses the signin:PrincipalArn condition key to exempt your excluded principal. This key supports all principal types: root user, AWS Identity and Access Management (IAM) user, federated user, and role.

The post-authentication statement evaluates the signin:AuthorizeOAuth2Access and signin:CreateOAuth2Token actions. AWS Sign-In evaluates these actions after authentication, when it issues the tokens that establish the console session. These actions do not support the signin:PrincipalArn key. Instead, they use aws:PrincipalArn, which resolves to the authenticated principal.

The aws:ResourceAccount value is the recipient account ID. AWS Sign-In pulls it automatically from your caller credentials, so you do not set it yourself. For the full list of supported actions and condition keys, including which keys apply at each phase and to each principal type, see Controlling console access with resource-based policies and resource control policies and AWS Sign-In condition keys reference.

Step 2: Turn on sign-in policy enforcement for your account

This step turns on enforcement of the policy you created in Step 1. Until you run this step, the resource permission statements you created in Step 1 have no effect.

5. Turn on enforcement of sign-in policies using the following command:

aws signin put-console-authorization-configuration \
  --target-id <account-id> \
  --region us-east-1

6. Verify the command succeeded by checking for a “consoleAuthorizationEnabled": true in the output.

Example output:

{
“Output": {
“consoleAuthorizationEnabled": true,
“scope": “ACCOUNT”,
“targetId": "<account-id>"
}
}

7. You can also verify the configuration by executing the get-console-authorization-configuration command as shown below:

aws signin get-console-authorization-configuration \
  --target-id <account-id> \
  --region us-east-1

8. To disable enforcement or remove individual statements, use delete-console-authorization-configuration or delete-resource-permission-statement. For more details, see Controlling console access with resource-based policies and resource control policies in the AWS Sign-In User Guide.

Verifying the implementation

Now that enforcement is active, sign-in attempts are evaluated against your resource-based policy. Verify the behavior by testing sign-in from different network conditions.

Scenario 1: Allowed sign-in from the corporate network

A principal signing in from the allowed corporate IP range or VPC succeeds normally. The CloudTrail event shows ConsoleLogin:Success

Example CloudTrail event details for successful console sign-in:

{
    "userIdentity": {
        "type": "AssumedRole",
        "principalId": "AROAEXAMPLEID:Dev1",
        "arn": "arn:aws:sts::123456789123:assumed-role/Developer/Dev1",
        "accountId": "123456789123"
    },
    "eventTime": "2026-06-09T19:20:38Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "ConsoleLogin",
    "awsRegion": "us-east-1",
    "sourceIPAddress": "192.0.2.100",
    "responseElements": {
        "ConsoleLogin": "Success"
    },
    "eventID": "dd004e78-6447-4f56-8d2d-a795da66f598",
    "readOnly": false,
    "eventType": "AwsConsoleSignIn",
    "managementEvent": true,
    "recipientAccountId": "123456789123",
    "eventCategory": "Management"
}

Scenario 2: Denied sign-in from an unexpected network

A principal signing in from a network other than the allowed IP address range or a VPC endpoint attached to the source VPC, is blocked. The CloudTrail event shows ConsoleLogin: Failure with an error message identifying the policy that caused the denial:

Example CloudTrail event details for failed console sign-in:

{    
"userIdentity": {
    "type": "IAMUser",
    "accountId": "123456789123",
    "accessKeyId": "",
    "userName": "Dev1"
    },
    "eventTime": "2026-06-09T19:20:38Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "ConsoleLogin",
    "awsRegion": "us-east-1",
    "sourceIPAddress": "198.51.100.76",
    "userAgent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/148.0.0.0 Safari/537.36",
    "errorCode": "AccessDenied",
    "errorMessage": "Authorization denied because of a resource-based policy",
    "requestParameters": null,
    "responseElements": {
        "ConsoleLogin": "Failure"
    },
"eventID": "d88a7543-ae89-4186-b1b6-d3116413f2ee",
"readOnly": false,
"eventType": "AwsConsoleSignIn",
"managementEvent": true,
"recipientAccountId": "123456789123",
"eventCategory": "Management"
}

The error message field shows the policy type that caused the denial: “Authorization denied because of a resource-based policy”.

Scaling with RCPs

The steps above apply a Sign-in resource-based policy to a single account. For organizations managing many accounts, RCPs offer a better path: they can be attached at the organization, OU, or account level in AWS Organizations and apply automatically to every account in scope. To view an RCP example, see here .

When a sign-in to the console is denied because of an RCP, the error message field shows the denial as “Authorization denied because of a resource control policy”.

Extending with Console Private Access and data perimeters

The sign-in resource-based policy you created controls which networks can reach your account’s sign-in flow. AWS Management Console Private Access adds a complementary control: from within your network, it limits console access to a known set of AWS accounts, preventing sign-in to unexpected AWS accounts.

Together, these capabilities contribute to a data perimeter for console access:

  • Network perimeter: Sign-in resource-based policies and RCPs restrict console sign-in to expected networks (corporate IP ranges, VPCs).
  • Identity perimeter: Sign-in resource-based policy and RCP ensure only trusted identities can sign in to the console. Console VPC endpoint policy and Sign-in VPC endpoint policy ensure only trusted identities can use the console from your VPC.
  • Resource perimeter: Sign-in VPC endpoint policy and Console VPC endpoint policy restrict which AWS accounts are reachable from your network.

The controls in this post focus on console access. To extend these perimeters to other AWS services and broader implementation scenarios, see the Data perimeter policy examples repository and the Data Perimeters Blog Post Series.

Conclusion

By using sign-in resource-based policies and RCPs, you can restrict AWS Management Console access to expected networks. These controls are available at no additional cost in all AWS commercial Regions.

To get started, see the AWS Sign-in User Guide. For organization-wide enforcement, see Resource control policies in the AWS Organizations User Guide.

If you have feedback about this post, submit comments in the Comments section below.


Swara Gandhi

Swara Gandhi is a Senior Solutions Architect on the AWS Identity Solutions team. She works on building secure and scalable end-to-end identity solutions. She is passionate about everything identity, security, and cloud.

Rishi Tripathy

Rishi Tripathy

Rishi is a Principal Product Manager on the AWS Identity and Access Management (IAM) team. He focuses on access control mechanisms that help enterprises secure their AWS environments at scale. He is passionate about building security primitives that are straightforward to adopt and hard to misconfigure.

Autonomous troubleshooting for Medallion Architecture with AWS DevOps Agent and Apache Spark Troubleshooting Agent

Post Syndicated from Mohammad Sabeel original https://aws.amazon.com/blogs/big-data/autonomous-troubleshooting-for-medallion-architecture-with-aws-devops-agent-and-apache-spark-troubleshooting-agent/

Every minute of data processing pipeline downtime delays business decisions, stalls downstream analytics, drives revenue loss, and erodes stakeholder confidence. Teams that run Medallion Architecture pipelines—a common data lakehouse pattern where data flows through bronze, silver, and gold layers with increasing quality—face cascading failures that impact revenue-critical reporting and machine learning workloads. As you scale these multi-stage pipelines with Amazon Managed Workflows for Apache Airflow (MWAA), AWS Glue, and Amazon Redshift, troubleshooting failures becomes increasingly complex. When a mission-critical job fails, an engineer must sift through gigabytes of logs across interconnected systems. This means spending hours on incident investigations, examining execution timelines and resource metrics, and cross-referencing findings with Amazon CloudWatch and recent deployment changes to find the root cause. This requires deep familiarity with the underlying technologies, expertise not every team member has. When the right engineer is unavailable during off-hours, pipeline downtime extends and downstream consumers wait. The cycle of detect, investigate, fix, and repeat is costly and entirely reactive. A proactive operational model moves issue identification upstream, catching and addressing problems before they disrupt your data pipelines.

In this post, we show you how to diagnose multi-layer Medallion Architecture pipeline failures in minutes using AWS DevOps Agent with Apache Spark Troubleshooting Agent integrated as an MCP server.

What is AWS DevOps Agent and Apache Spark Troubleshooting Agent?

AWS DevOps Agent is an autonomous investigation agent powered by AI that automatically diagnoses operational issues across your AWS environment. When a failure occurs, the agent independently gathers evidence from logs, metrics, and configurations across interconnected services, identifies the root cause, and delivers actionable remediation steps, all without human intervention. It integrates with your existing workflows through webhooks and delivers findings directly to communication channels like Slack. With AWS DevOps Agent, you can replace the reactive cycle of detect, investigate, fix, and repeat with autonomous, proactive troubleshooting. The agent acts as your always-on, on-call engineer, starting its investigation the moment a failure occurs, whether during business hours or in the middle of the night.

Apache Spark Troubleshooting Agent is an AI-powered, fully managed Model Context Protocol (MCP) server that data engineers can use to diagnose Spark application failures across Amazon EMR, AWS Glue, and Amazon SageMaker AI Notebooks using natural language. It automatically correlates Spark History Server data, distributed executor logs, and configuration patterns to identify root causes and deliver actionable recommendations. This removes hours of manual investigation across multiple consoles and log files.

Use case

The following sections walk through a common Medallion Architecture failure scenario and show how autonomous troubleshooting resolves it.

The scenario

Consider this scenario: a gold layer AWS Glue job fails with “Missing data for not-null field.” The logs don’t reveal the actual problem. The root cause is a subtle data quality issue introduced upstream in the silver layer, a job that succeeded without errors. Without autonomous troubleshooting, you would manually trace data lineage across Amazon Simple Storage Service (Amazon S3), Amazon Redshift, and multiple AWS Glue job logs to find the source.

The solution

When integrated with the Apache Spark Troubleshooting Agent, AWS DevOps Agent identifies the gold layer Amazon Redshift write failure, traces it back to silver layer data corruption, and provides detailed root causes and actionable recommendations. The investigation typically completes within 3 to 5 minutes.

Solution overview

The following diagram shows the Medallion Architecture data flow across bronze, silver, and gold layers.

Medallion Architecture data flow showing the bronze layer in Amazon S3, the silver layer in Amazon S3 and Amazon Redshift, and the gold layer in Amazon Redshift, with Amazon MWAA orchestrating AWS Glue jobs and AWS DevOps Agent investigating failures

The architecture flow includes the following steps:

  1. Amazon MWAA triggers the Medallion pipeline directed acyclic graph (DAG), orchestrating three AWS Glue jobs sequentially: bronze layer, silver layer, and gold layer.
  2. The bronze layer job generates 50,000 synthetic ecommerce order records and writes raw Parquet files to Amazon S3.
  3. The silver layer job reads bronze data from Amazon S3, applies transformations, and writes the results to two destinations in parallel: Amazon S3, and Amazon Redshift (filtered, cleaned, and augmented data in the silver_ecommerce table). This job silently introduces data corruption in approximately 8 percent of total_amount values.
  4. The gold layer job reads from the Amazon Redshift silver_ecommerce table, performs aggregation, and attempts to write business-level aggregates back to the Amazon Redshift gold_ecommerce_summary table. If upstream data corruption introduces NULL values, this job fails with “Missing data for not-null field” because those NULL values violate the NOT NULL constraint.
  5. When the gold layer job enters a FAILED state, Amazon EventBridge captures the AWS Glue Job State Change event and invokes an AWS Lambda function. The Lambda function retrieves webhook credentials from AWS Secrets Manager, constructs an HMAC-signed event payload containing the job name, run ID, and error details, and sends it to AWS DevOps Agent.
  6. AWS DevOps Agent receives the HTTP POST request to the webhook and starts an autonomous investigation. It authenticates with Amazon Cognito using the OAuth 2.0 client credentials flow, then sends an MCP request through Amazon Bedrock AgentCore Gateway. The AgentCore Gateway invokes a Signature Version 4 (SigV4) Proxy Lambda, which signs the request and forwards it to the Apache Spark Troubleshooting Agent MCP Server. The MCP Server analyzes Spark event logs, executor metrics, and error stack traces for the failed gold job.
  7. AWS DevOps Agent delivers the investigation to your configured Slack channel. The delivery includes root cause analysis, upstream data lineage back to the silver layer corruption, and step-by-step remediation recommendations.

Walkthrough

In the following sections, you deploy a three-layer Medallion Architecture pipeline that processes ecommerce order data. Complete the steps to get started with autonomous troubleshooting using AWS DevOps Agent.

Prerequisites

Before you begin, verify that you have the following:

  • An AWS account. Your AWS Identity and Access Management (IAM) user or role must have the following permissions:
    • iam:CreateRole, iam:AttachRolePolicy, iam:PutRolePolicy
    • lambda:CreateFunction, lambda:AddPermission
    • glue:CreateJob, glue:StartJobRun
    • redshift:CreateCluster, redshift:GetClusterCredentials
    • airflow:CreateEnvironment
    • events:PutRule, events:PutTargets
    • sqs:CreateQueue
    • secretsmanager:CreateSecret
    • kms:CreateKey
    • ec2:CreateVpc, ec2:CreateSubnet, ec2:CreateSecurityGroup
    • cloudformation:CreateStack, cloudformation:DescribeStacks
    • Alternatively, you can use the AdministratorAccess managed policy for simplicity in a dev/test environment.
  • AWS Command Line Interface (AWS CLI) version 2.30.0 or later, installed and configured with appropriate credentials.
  • (Optional) A Slack workspace if you want investigation results delivered to a channel.

Set up AWS DevOps Agent

In this section, you configure AWS DevOps Agent to receive and investigate pipeline failure events. This involves three tasks: creating an Agent Space (your investigation workspace), optionally connecting a Slack channel for notifications, and generating a webhook endpoint that your pipeline uses to send failure alerts to the agent.

Create an Agent Space

  1. Open the AWS DevOps Agent console.
  2. Choose Create Agent Space.
  3. Enter a name (for example, medallion-troubleshooting).
  4. Choose Create.

Connect Slack integration (optional)

If you use Slack for internal communication, you can configure it to receive investigation results.

  1. In the AWS DevOps Agent console, go to Agent Spaces, select medallion-troubleshooting and then Communications.
  2. Choose Add integration and choose Slack.
  3. Choose Next to allow AWS DevOps Agent to access your Slack workspace, and choose Allow.
  4. Provide the Slack workspace and the Channel ID where you want investigation results delivered, then choose Next.
  5. Enter the following command in your channel chat to complete the integration: /invite @AWS DevOps Agent.
    • While running this command, when prompted, choose the correct region where the Agent Space is provisioned.

Create a webhook

  1. In your Agent Space, go to Webhooks.
  2. Choose Add webhook and choose Next on the two following pages.
  3. Choose Generate URL and secret key, and give the webhook a name (for example, medallion-failure-webhook).
  4. After creation, copy and save the Webhook URL (HTTPS endpoint) and Secret Key. You can also choose Download .csv to save this information to a secure location. Select the checkbox labeled I’ve saved and stored my URL and secret key, then choose Add.

Note the Webhook URL and Secret Key for later. You provide them as parameters when you create the AWS CloudFormation stack.

Deploy the AWS CloudFormation stack

The AWS CloudFormation template deploys the full Medallion Architecture pipeline. This includes an Amazon Virtual Private Cloud (Amazon VPC) with private subnets, an Amazon Redshift cluster (ra3.xlplus, single-node), and three AWS Glue jobs. It also creates an Amazon MWAA environment, Amazon EventBridge rules, AWS Lambda functions, and an AgentCore Gateway with Amazon Cognito OAuth authentication.

You can deploy the stack using one of two methods. Use Option A if you prefer a visual, guided experience through the AWS Management Console. Use Option B if you prefer working from the command line or need to integrate the deployment into a script or automation workflow.

Before you start, download the CloudFormation template from GitHub.

Option A: AWS Management Console (recommended)

  1. Open the AWS CloudFormation console and choose Create stack → With existing resources (import resources) or Upload a template file.
  2. Choose Choose file, select the downloaded blog-medallion-stack.yaml, then choose Next.
  3. For Stack name, enter medallion-troubleshooting.
  4. Fill in the parameters:
    • For WebhookUrl, enter your AWS DevOps Agent webhook URL (from Agent Space settings).
    • For WebhookSecret, enter the webhook secret for authentication.
  5. Choose Next, select I acknowledge that AWS CloudFormation might create IAM resources with custom names, then choose Submit.

Option B: AWS CLI

aws cloudformation create-stack \
    --stack-name medallion-troubleshooting \
    --template-body file://blog-medallion-stack.yaml \
    --parameters \
        ParameterKey=WebhookUrl,ParameterValue=<YOUR-WEBHOOK-URL> \
        ParameterKey=WebhookSecret,ParameterValue=<YOUR-WEBHOOK-SECRET> \
    --capabilities <CAPABILITY_NAMED_IAM> \
    --region <YOUR-REGION>

Replace the placeholder values:

  • YOUR-WEBHOOK-URL – Your AWS DevOps Agent webhook URL (from Agent Space settings).
  • YOUR-WEBHOOK-SECRET – The webhook secret for authentication.
  • YOUR-REGION – The AWS Region.

Wait for the stack status to show CREATE_COMPLETE. In our testing, this took approximately 30–40 minutes.

Retrieve Amazon Cognito client credentials

After the stack is deployed, it creates an Amazon Cognito user pool with an OAuth 2.0 client for AWS DevOps Agent authentication. Retrieve the client secret using the command below. The --user-pool-id  and CognitoClientId needs to be copied from the stack outputs.

aws cognito-idp describe-user-pool-client \
    --user-pool-id <UserPoolId-from-outputs> \
    --client-id <CognitoClientId-from-outputs> \
    --query UserPoolClient.ClientSecret \
    --output text --region <YOUR-REGION>

Replace YOUR-REGION with the actual AWS Region value, and save this value for the MCP Server registration in the following step.

Register the Spark Troubleshooting MCP Server

The Spark Troubleshooting MCP Server gives AWS DevOps Agent the ability to analyze Apache Spark event logs, executor metrics, and error stack traces from your AWS Glue jobs. By registering this server, you connect the agent to the diagnostic tooling it needs to autonomously investigate pipeline failures.

To register the MCP Server in AWS DevOps Agent, complete the following steps:

  1. In the AWS DevOps Agent console, go to Agent Spaces, select medallion-troubleshooting and then Capabilities.
  2. In the MCP Servers section, choose Add or Add Source.
  3. Find New MCP Server Registration and choose Register.
  4. For Name, enter sparkagent.
  5. For Endpoint URL, enter the AgentCoreGatewayUrl value from the stack outputs.
  6. For Description, enter Apache Spark Troubleshooting MCP Server via AgentCore Gateway.
  7. Leave Enable Dynamic Client Registration cleared.
  8. Leave Connect to endpoint using a private connection cleared, then choose Next.Registration page for the Apache Spark Troubleshooting MCP Server in the AWS DevOps Agent console, showing endpoint URL and description fields
  9. Under Authorization Flow, select OAuth Client Credentials, and choose Next.
  10. For Client ID, enter the CognitoClientId value from the stack outputs.
  11. For Client Secret, enter the value you retrieved in the preceding step.
  12. For Exchange URL, enter the CognitoTokenEndpoint value from the stack outputs.
  13. For Add Scope, enter <stack-name>-mcp-proxy/invoke. For example, medallion-troubleshooting-mcp-proxy/invoke.
  14. Choose Next, review your configuration, and choose Add.
  15. Once you choose Add, on the following screen, click on the checkbox next to the spark___analyze_spark_workload. This is the root cause analysis tool which provides detailed troubleshooting for failed Apache Spark workloads.
    Selecting the tool within the AWS Managed Apache Spark Troubleshooting MCP server
  16. Choose Save as a last step. You will see the MCP Server associated successfully message on the top.
    Confirmation showing the successful Integration of AWS DevOps Agent Space with Apache Spark Troubleshooting MCP Server

See AWS DevOps Agent in action

Now that you have completed the prerequisites, you can see AWS DevOps Agent in action. Go to the Amazon MWAA Airflow Environments UI and click on Open Airflow UI under Airflow UI. It will open in a new browser tab. In the Airflow console, locate and manually trigger the medallion_architecture_pipeline DAG.

Amazon MWAA Airflow console showing the medallion_architecture_pipeline DAG with the Trigger DAG action selected

Amazon MWAA Airflow UI showing the medallion_architecture_pipeline DAG with bronze, silver, and gold tasks listed sequentially

The DAG runs three AWS Glue jobs sequentially:

  1. Bronze layer – This job generates 50,000 ecommerce order records and writes them to Amazon S3 as Parquet files.
  2. Silver layer – This job applies transformations and loads the results to both Amazon S3 and Amazon Redshift. It also silently injects approximately 8 percent of total_amount values with $ prefix strings, introducing hidden data corruption.
  3. Gold layer – This job reads from Amazon Redshift, casts total_amount to numeric (producing NULL values for the $-prefixed strings), and attempts to write aggregated results to the Amazon Redshift target table. It fails because the NULL values violate the NOT NULL constraint on revenue_total.

Amazon MWAA DAG run showing the bronze task succeeded, the silver task succeeded, and the gold task failed

With the components deployed and connected, the autonomous troubleshooting pipeline is ready to respond to failures. In this walkthrough, the silver layer job deliberately introduces data corruption to simulate a real-world data quality issue. This causes the gold layer job to fail, giving you the opportunity to see how AWS DevOps Agent responds.

As soon as the gold layer job fails, AWS DevOps Agent starts an autonomous investigation and uses the Apache Spark Troubleshooting MCP Server where needed.

Go to the AWS DevOps Management console and choose the medallion-troubleshooting under Agent Spaces. Next, select the Operator Access button. This will redirect you to Operator Console where you will see that the incident investigation automatically started in 1-2 minutes post Gold layer job failure.

After the investigation completes, AWS DevOps Agent presents its findings within the incident analysis. The results are organized into two sections.

Root cause identified by AWS DevOps Agent

The agent identifies the underlying cause of the failure, tracing the gold layer write error back to data corruption introduced in the upstream silver layer AWS Glue job.

Root cause analysis from AWS DevOps Agent showing the gold layer write error traced back to silver layer data corruption

Mitigation plan generated by AWS DevOps Agent

On choosing Generate Mitigation Plan, the agent provides step-by-step remediation recommendations to resolve the issue and prevent recurrence.

Mitigation plan from AWS DevOps Agent listing remediation steps to fix the silver layer data corruption and prevent recurrence

AWS DevOps Agent sends a notification to Slack

Slack channel showing the AWS DevOps Agent investigation summary with root cause identification and upstream data lineage trace

Typically, within 3–5 minutes, the agent delivers a detailed investigation in Slack that includes root cause identification, upstream data lineage tracking, and an actionable recommendation.

You have deployed an autonomous troubleshooting pipeline for Medallion Architecture data pipelines. The pipeline runs using AWS Glue, Amazon Redshift, and Amazon MWAA, with AWS DevOps Agent providing autonomous investigation. The agent traced a gold layer Amazon Redshift write failure back to a silver layer data quality issue. This type of diagnosis would typically require hours of manual investigation by an engineer with deep expertise in Apache Spark, Amazon Redshift, and data pipeline architecture. AWS DevOps Agent completed it autonomously within minutes.

If you need human assistance, you can use the Ask for human support feature within AWS DevOps Agent to open a case with AWS Support, automatically populated with relevant investigation context.

Enhanced investigations with AWS DevOps Agent Skills

AWS DevOps Agent autonomously investigates failures out of the box. You can enhance its diagnostic depth using Skills, a feature that provides the agent with domain-specific guidance tailored to your environment.

For Medallion Architecture pipelines, you can create Skills that instruct the agent to check for data type mismatches between pipeline layers when Amazon Redshift COPY errors occur, cross-reference silver layer data quality metrics with gold layer aggregation failures, or follow your internal runbook for escalating data quality issues to the upstream data engineering team.

To configure Skills, go to your Agent Space in the AWS DevOps Agent console and choose the Skills tab.

Clean up

To avoid incurring future charges, delete the resources you created during this walkthrough promptly after you finish testing.

To clean up resources, complete the following steps:

  1. Deregister the MCP Server. In the AWS DevOps Agent console, go to your Agent Space and choose the Capabilities tab. In the MCP Servers section, choose the sparkagent server, then choose Deregister.
  2. Delete the webhook. In your Agent Space, go to the Webhooks tab. Choose the medallion-failure-webhook, then choose Delete.
  3. Empty the Amazon S3 buckets. Open the Amazon S3 console. Locate the buckets created by the stack (their names start with medallion-troubleshooting). For each bucket, choose Empty, enter permanently delete to confirm, and choose Empty.
  4. Delete the AWS CloudFormation stack. Open the AWS CloudFormation console. Choose the medallion-troubleshooting stack, then choose Delete. Alternatively, run the following command:
aws cloudformation delete-stack \
    --stack-name medallion-troubleshooting \
    --region <your-region>

Wait for the stack deletion to complete.

  1. Delete any retained Amazon S3 buckets. Some Amazon S3 buckets might have a DeletionPolicy of Retain and aren’t automatically deleted with the stack. Return to the Amazon S3 console, locate any remaining buckets created by the stack, empty them using the process in the preceding step, and then choose Delete for each bucket.

Conclusion

In this post, you deployed an autonomous troubleshooting pipeline for Medallion Architecture data pipelines using AWS Glue, Amazon Redshift, Amazon MWAA, and AWS DevOps Agent. The agent traced a gold layer Amazon Redshift write failure back to a silver layer data quality issue—a diagnosis that would typically require hours of manual investigation by an engineer with deep expertise across multiple services.

As your data pipelines grow in complexity, so does the challenge of diagnosing failures that span multiple layers and services. AWS DevOps Agent reduces your mean time to resolution by autonomously investigating incidents the moment they occur, whether during business hours or at 2 AM. Your on-call engineers spend less time sifting through logs and more time building reliable data infrastructure. By shifting from reactive firefighting to autonomous, proactive troubleshooting, you can improve pipeline reliability, protect downstream analytics and machine learning workloads, and maintain stakeholder confidence in your data platform.

To learn how to structure Agent Spaces for investigation accuracy, scope resource access, and use infrastructure as code to streamline deployment, see Best practices for deploying AWS DevOps Agent in production. To learn how to evaluate and choose the right lakehouse pattern for your needs, see Navigating architectural choices for a lakehouse using Amazon SageMaker. For more about Apache Spark Troubleshooting Agent, see Introducing the Apache Spark Troubleshooting Agent for Amazon EMR and AWS Glue.

Next steps

Now that you have set up autonomous troubleshooting for your Medallion Architecture pipeline, consider exploring the following:


About the authors

Mohammad Sabeel

Mohammad Sabeel

Mohammad is a Senior Technical Account Manager (TAM) at Amazon Web Services (AWS) with over 14 years of experience in Information Technology (IT). As a member of the Technical Field Community for Analytics team, he is a subject matter expert in Analytics services including AWS Glue, Amazon Managed Workflows for Apache Airflow (MWAA), and Amazon Athena. Sabeel provides strategic guidance and proactive technical support to enterprise and ISV customers, helping them optimize their data analytics solutions, build resilient architectures, and accelerate cloud adoption. With deep subject matter expertise, he enables organizations to build scalable, efficient, and cost-effective data processing pipelines.

Ishan Gaur

Ishan Gaur

Ishan is a Principal Cloud Engineer at AWS. He has worked in the Analytics domain for the last 17 years, now focused on data analytics, AI/ML operations, and proactive cloud optimization. He works with enterprise customers to design resilient data pipelines, automate incident response, and adopt GenAI-powered services and operational tools. He’s passionate about turning reactive support patterns into proactive, self-healing architectures.

Getting your SMS short code production-ready with AWS End User Messaging

Post Syndicated from Harshvardhan Chunawala original https://aws.amazon.com/blogs/messaging-and-targeting/getting-your-sms-short-code-production-ready-with-aws-end-user-messaging/

Getting your Short Message Service (SMS) short code production-ready requires you to configure the Amazon Web Services (AWS) infrastructure that controls how your messages are sent, monitored, and protected. You have provisioned your short code, and it is active on carrier networks. In this post, we walk through that setup using AWS End User Messaging SMS, covering 12 configuration steps from compliance through phased traffic migration. Total estimated time is 2 to 4 hours of configuration plus 1 to 3 business days for limit increase approvals.mess

The guide to SMS short codes with AWS End User Messaging covers the application and registration process up through provisioning. This post picks up from that point and provides an operational readiness walkthrough that takes you from “Active” status to confidently sending your first production message, including a final validation step to confirm readiness.

The following diagram shows the end-to-end message flow and event routing architecture covered in this walkthrough.

End-to-end SMS short code architecture showing message flow from sender through AWS End User Messaging SMS to carriers and recipient handsets, with event routing to Amazon CloudWatch, Amazon Simple Notification Service (Amazon SNS), and Amazon Data Firehose destinations

Prerequisites

You need the following to follow along with this walkthrough:

  1. An AWS account with access to the AWS End User Messaging SMS console.
  2. A short code with Active status in the AWS Management Console (carrier provisioning finished).
  3. Permissions to create AWS Identity and Access Management (IAM) roles, Amazon CloudWatch Log Groups, and Amazon Simple Notification Service (Amazon SNS) topics.
  4. AWS Command Line Interface (AWS CLI) v2 or an AWS SDK installed and configured.
  5. Your approved registration documentation, including the service name, keyword responses, and message templates submitted to carriers.

Step 1: Verify your short code is active and delivering

Navigate to the AWS End User Messaging SMS console, choose Phone numbers, and locate your provisioned short code. Confirm that the status shows Active, then send a test message to a phone number you control using the SendTextMessage API or the console test feature. Verify delivery on your handset.

Carrier-side activation can take up to 24 to 48 hours to fully propagate across all networks after provisioning finishes. If the console shows Active but your test message does not arrive, submit a support case so the team can verify propagation status with the carrier.

You can also verify using the AWS CLI:

aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+15555550100" \
    --origination-identity "12345" \
    --message-body "Test message from short code" \
    --message-type TRANSACTIONAL \
    --configuration-set-name "prod-otp-shortcode"
# Replace +15555550100 with your test phone number, 12345 with your short
# code, and prod-otp-shortcode with your configuration set name from Step 3.

Step 2: Configure keywords and verify message compliance

US carriers require every short code to respond to HELP and STOP keywords. You defined these during your registration, and this step confirms they are configured correctly in your account.

In the SMS console, choose Phone numbers, select your short code, and choose the Keywords tab. Verify that STOP returns the opt-out response you submitted during registration, and that HELP returns your support contact response (which must include a phone number or email). Add any custom keywords your use case requires, such as YES for double opt-in confirmation flows. You can manage keywords programmatically using the PutKeyword API.

To add or update a keyword programmatically:

aws pinpoint-sms-voice-v2 put-keyword \
    --origination-identity "12345" \
    --keyword "YES" \
    --keyword-message "You have confirmed your subscription to Acme Health Alerts. Msg&data rates may apply. Reply STOP to opt out." \
    --keyword-action AUTOMATIC_RESPONSE
# Replace 12345 with your short code, YES with your custom keyword, and the
# keyword-message text with your approved response.

To verify your current keyword configuration:

aws pinpoint-sms-voice-v2 describe-keywords \
    --origination-identity "12345"
# Replace 12345 with your short code.

Beyond keyword configuration, carrier compliance does not end at registration approval. The content you send in production must stay aligned with what carriers reviewed and approved. Here is what to keep consistent.

Use the exact brand or program name from your approved registration across all keyword responses, confirmation messages, and outbound templates. If carriers approved your registration under “Acme Health Alerts,” every message your short code sends should reference that name. Mixing variations creates inconsistencies that auditors flag during reviews. For example, do not use the company name in one message and the product name in another.

Your HELP, STOP, and confirmation responses must match the templates submitted during registration. Do not add or remove opt-out language, change frequency disclosures, or alter customer care contact details post-approval without updating the registration through a support case. If your organization operates multiple domains, use the domain documented in the registration. For example, you might have one domain for the application and another for marketing. Carrier reviewers cross-reference message content, opt-in screenshots, and privacy policy URLs with what was submitted.

Humans conduct carrier reviews, and message content that is concise and limited to the essentials is reviewed consistently. All messages must remain under 160 characters.

Step 3: Create a configuration set with event destinations

A configuration set controls where your SMS delivery events are streamed and which event types are captured. Without one, you are limited to the basic events that AWS End User Messaging SMS sends to Amazon EventBridge by default. These default events omit recipient details and full carrier response context.

Create a configuration set with a descriptive name such as prod-otp-shortcode or marketing-sc-us. Then create at least one event destination. The three main options are Amazon CloudWatch Logs (for operational monitoring and alarming), Amazon SNS (for real-time event fanout to downstream systems), and Amazon Data Firehose (for durable archival and analytics).

Amazon Data Firehose typically delivers to an Amazon Simple Storage Service (Amazon S3) bucket, where you can query delivery history using Amazon Athena for compliance audits or delivery pattern analysis.

# Create the configuration set
aws pinpoint-sms-voice-v2 create-configuration-set \
    --configuration-set-name "prod-otp-shortcode"

# Add a CloudWatch Logs event destination
aws pinpoint-sms-voice-v2 create-event-destination \
    --configuration-set-name "prod-otp-shortcode" \
    --event-destination-name "otp-delivery-logs" \
    --matching-event-types TEXT_DELIVERED TEXT_FAILED TEXT_QUEUED TEXT_CARRIER_UNREACHABLE TEXT_TTL_EXPIRED \
    --cloud-watch-logs-destination '{
        "IamRoleArn": "arn:aws:iam::123456789012:role/SMSEventsToCloudWatch",
        "LogGroupArn": "arn:aws:logs:us-east-1:123456789012:log-group:/aws/sms/prod-otp-shortcode"
    }'
# Replace prod-otp-shortcode with your configuration set name, otp-delivery-logs
# with a descriptive destination name, and the ARN values with your IAM role ARN
# (must have logs:PutLogEvents permission) and CloudWatch Log Group ARN.

Important: When sending messages with SendTextMessage, always specify your ConfigurationSetName parameter so events route to the appropriate destination.

Required event types

Event type Description
TEXT_DELIVERED Message successfully delivered to recipient handset.
TEXT_FAILED Message delivery failed.
TEXT_QUEUED Message accepted and queued for delivery.
TEXT_CARRIER_UNREACHABLE Carrier network unreachable.
TEXT_TTL_EXPIRED Message expired before delivery.

For a detailed walkthrough of configuration sets including multi-tenant architectures, see How to send SMS using configuration sets with AWS End User Messaging.

Step 4: Create a phone pool and associate your short code

A pool is a logical container that groups origination identities and controls routing behavior. Creating one gives you deterministic control over which number sends your messages and how opt-outs are enforced.

# Create the pool
aws pinpoint-sms-voice-v2 create-pool \
    --origination-identity "12345" \
    --iso-country-code "US" \
    --message-type TRANSACTIONAL

# Disable shared routes so only your short code is used
aws pinpoint-sms-voice-v2 update-pool \
    --pool-id "pool-1234567890abcdef0" \
    --shared-routes-enabled false
# Replace 12345 with your short code, US with your destination country code,
# and pool-1234567890abcdef0 with the Pool ID returned by create-pool.

Configuration parameters

Parameter Recommended value Rationale
Pool name us-otp-pool Descriptive, environment-prefixed.
SharedRoutesEnabled False Prevents fallback to shared routes; only your short code is used.
Opt-out list Associate one Manages opt-out state per use case.
IsoCountryCode US Restricts to destination country your short code serves.

If you operate multiple use cases on separate short codes, create a dedicated pool for each. For example, use one short code for one-time password (OTP) traffic and another for transactional notifications. This isolation means a recipient opting out of marketing messages does not lose access to authentication codes.

Step 5: Request your throughput increase

Short codes start at a default of 100 messages per second (MPS). If your production volume will exceed this, request an increase before your launch date rather than after traffic is flowing.

Create a case in the AWS Support Center, choose Service limit increase, then choose End User Messaging SMS. Provide your short code phone number, requested MPS, use case description, and expected peak volume. Allow 1 to 3 business days for processing.

To estimate your required MPS:

Required MPS = (Peak hourly volume / 3,600) x 2

Short codes support scaling to thousands of MPS, so start with a value that covers your expected peak and request further increases as traffic grows.

Step 6: Request a spending limit increase

AWS accounts have a default monthly SMS spending limit. To keep delivery uninterrupted at your expected volume, request an increase that accommodates your projected monthly spend before you begin sending.

Create a support case under Service limit increase > End User Messaging SMS > Account Spend Threshold. Provide your estimated monthly spend, use case description, and website URL.

For details, see Requesting increases to your monthly SMS spending quota.

Step 7: Restrict destination countries

If your short code serves a single country (US-only, for example), restrict sending to that country. This protects your account from artificially inflated traffic (SMS pumping). In pumping attacks, messages are routed to international premium-rate numbers, generating significant charges.

In the SMS console, navigate to Account settings, then choose Countries and keep only the countries you intend to send to. The pool-level IsoCountryCode restriction from Step 4 provides an additional enforcement layer at the sending path. Combining account-level country restrictions with pool-level country codes gives you two independent controls that both must be satisfied before a message is sent internationally.

For a detailed walkthrough on SMS fraud prevention controls, see Defending against SMS pumping: new AWS features to help combat artificially inflated traffic.

Step 8: Set up monitoring and alarms

With event destinations configured in Step 3, build proactive alerting that surfaces delivery trends before they affect your end users.

Alarm Metric / Source Threshold
Delivery success rate CloudWatch SMS metrics Alert when below 95%.
Spend threshold CloudWatch billing metric Alert at 80% of monthly limit.
Delivery failures Amazon EventBridge rule on TEXT_FAILED Route to Amazon SNS topic or AWS Lambda.
Carrier unreachable Amazon EventBridge rule on TEXT_CARRIER_UNREACHABLE Route to Amazon SNS topic or AWS Lambda.

Build a CloudWatch dashboard showing messages sent per minute, success versus failure breakdown, and spend accumulation over time.

You can also configure Amazon EventBridge to notify you of registration status changes. AWS End User Messaging SMS publishes events for statuses including REQUIRES_UPDATES, REVIEWING, and PROVISIONING, which is useful if a carrier requests changes during a proactive audit after your short code is already active.

For metric details, see Monitoring SMS activity with Amazon CloudWatch.

Step 9: Track OTP verification success (if applicable)

If your short code delivers OTP or two-factor authentication (2FA) codes, track end-to-end verification success in addition to carrier delivery receipts. A “delivered” status at the carrier level does not confirm the end user received and entered the code.

Tracking verification rates gives you insight into latency patterns when codes expire before arrival, geographic delivery trends, and opportunities to improve conversion. Some use cases involve asynchronous processing where several minutes of computation occur before the SMS is sent. For these, measure the full round-trip from the triggering action to message delivery. This separates application-side latency from carrier-side delivery latency.

For implementation guidance, see Track OTP success with AWS End User Messaging SMS feedback.

Step 10: Set up cost visibility

SMS costs include AWS charges plus per-message carrier surcharges. Setting up cost visibility from day one lets you track spend trends, catch anomalies early, and optimize over time.

Start by activating AWS Cost Explorer and creating a cost allocation tag for your SMS workload. Then configure an AWS Budget with threshold alerts. For example, you might notify at 80% of projected monthly spend. This gives you advance warning of unexpected cost increases, whether from traffic spikes, retry loops, or blocked-country leakage.

Step 11: Plan your traffic migration

A phased rollout validates delivery performance at each stage before you increase volume.

Start with a canary phase (Day 1 to 3) where you route 5 to 10% of traffic to the short code and monitor delivery rates, latency, and event logs. Move to a ramp phase (Day 3 to 7) at 50%, validating throughput and carrier-level delivery across your recipient base. Finish the full migration (Day 7+) at 100%. Decommission your previous origination identity only after confirming stability for at least 48 hours.

Step 12: Validate production readiness and send

Before declaring your short code production-ready, run through the following validation checks:

  1. Confirm your CloudWatch dashboard shows events flowing for TEXT_DELIVERED and TEXT_FAILED (from Step 3).
  2. Send a test message that triggers your STOP keyword. Verify the correct opt-out response is returned and the phone number appears in your opt-out list.
  3. Send a test message that triggers your HELP keyword. Verify the response matches your approved registration.
  4. Check your MPS quota in the support case response (from Step 5). Confirm it matches or exceeds your calculated peak.
  5. Review your country restrictions (from Step 7). Attempt to send a message to a blocked country and confirm it is rejected.
  6. Verify your CloudWatch alarm fires by temporarily lowering the threshold, or by checking that the alarm state is not INSUFFICIENT_DATA.

After all six checks pass, you are ready to begin your phased migration (Step 11) and scale to full production traffic. At this point, your short code is configured, monitored, compliant, and protected.

Automate with a validation script

You can use an AI coding assistant such as Kiro to generate a validation script tailored to your environment. Try a prompt like: “Write a boto3 script that validates my SMS short code is production-ready by checking Active status, HELP/STOP keywords, configuration set existence, and pool association using the pinpoint-sms-voice-v2 client.”

Refine the prompt with specifics from the following reference implementation, such as exact API names, filter parameters, and output format, to match your requirements.

The following script is an example of what that output looks like:

import boto3
import sys

SHORT_CODE = "12345"  # TODO: Replace with your short code (e.g., "67890")
POOL_ID = "pool-1234567890abcdef0"  # TODO: Replace with your pool ID from Step 4
CONFIG_SET_NAME = "prod-otp-shortcode"  # TODO: Replace with your configuration set name from Step 3

client = boto3.client("pinpoint-sms-voice-v2")

# Note: For accounts with many resources, implement NextToken pagination
# on describe_* calls. This script assumes results fit in a single page.


def check_short_code_active():
    """Step 1: Verify short code is Active."""
    response = client.describe_phone_numbers(
        Filters=[
            {"Name": "status", "Values": ["ACTIVE"]},
            {"Name": "number-type", "Values": ["SHORT_CODE"]}
        ]
    )
    numbers = [
        n for n in response["PhoneNumbers"]
        if n["PhoneNumber"] == SHORT_CODE
    ]
    assert len(numbers) > 0, f"Short code {SHORT_CODE} not found or not Active"
    print(f"[PASS] Short code {SHORT_CODE} is Active")


def check_keywords_configured():
    """Step 2: Verify HELP and STOP keywords exist."""
    response = client.describe_keywords(OriginationIdentity=SHORT_CODE)
    keyword_names = [kw["Keyword"].upper() for kw in response["Keywords"]]
    assert "STOP" in keyword_names, "STOP keyword not configured"
    assert "HELP" in keyword_names, "HELP keyword not configured"
    print("[PASS] HELP and STOP keywords configured")


def check_configuration_set():
    """Step 3: Verify configuration set exists."""
    response = client.describe_configuration_sets(
        ConfigurationSetNames=[CONFIG_SET_NAME]
    )
    assert len(response["ConfigurationSets"]) > 0, f"Configuration set {CONFIG_SET_NAME} not found"
    print(f"[PASS] Configuration set '{CONFIG_SET_NAME}' exists")


def check_pool_association():
    """Step 4: Verify pool exists and short code is associated to it."""
    response = client.describe_pools(PoolIds=[POOL_ID])
    assert len(response["Pools"]) > 0, f"Pool {POOL_ID} not found"

    # Verify short code is associated to the pool
    assoc_response = client.list_pool_origination_identities(PoolId=POOL_ID)
    identities = [
        oi["OriginationIdentity"]
        for oi in assoc_response["OriginationIdentities"]
    ]
    assert any(SHORT_CODE in oi for oi in identities), \
        f"Short code {SHORT_CODE} not associated with pool {POOL_ID}"
    print(f"[PASS] Pool '{POOL_ID}' exists and short code is associated")


if __name__ == "__main__":
    checks = [
        check_short_code_active,
        check_keywords_configured,
        check_configuration_set,
        check_pool_association,
    ]
    for check in checks:
        try:
            check()
        except Exception as e:
            print(f"[FAIL] {check.__doc__} - {e}")
            sys.exit(1)
    print("\nAll validation checks passed. Ready for production traffic.")

Cleaning up

If you created test resources while following this walkthrough, you can delete them through the AWS End User Messaging SMS console or with the API to avoid confusion with your production configuration. This includes a test configuration set, test pool, or test event destinations used for validation. Do not delete your production configuration set, pool, or keyword settings.

If you requested a test-level MPS increase or spending limit for validation, update these to your production values through a new support case before going live.

Quick reference checklist

Step Action Key API / Service
1 Verify short code is Active and test delivery SendTextMessage
2 Configure keywords and verify message compliance PutKeyword
3 Create configuration set with event destinations CreateConfigurationSet
4 Create pool and associate short code CreatePool, AssociateOriginationIdentity
5 Request MPS increase for expected throughput AWS Support
6 Request spending limit increase AWS Support
7 Restrict destination countries Console / UpdateAccount
8 Set up CloudWatch alarms and dashboards Amazon CloudWatch
9 Track OTP verification success (if applicable) SMS Feedback events
10 Set up cost visibility AWS Cost Explorer, AWS Budgets
11 Plan phased traffic migration Application-level routing
12 Validate production readiness and send All of the preceding

Conclusion

In this post, we walked through how to configure a newly provisioned SMS short code for production use with AWS End User Messaging SMS. The 12 steps cover keyword verification, message compliance, event monitoring, throughput planning, country restrictions, cost visibility, phased traffic migration, and a final production validation.

You can adapt the sequence to your specific use case and volume profile. For the full registration and application process, see A guide to SMS short codes with AWS End User Messaging. To start configuring, navigate to the AWS End User Messaging SMS console. For the full API reference, see the AWS End User Messaging SMS documentation.


About the author

Building and running custom code transformations without leaving your editor

Post Syndicated from David Hasani original https://aws.amazon.com/blogs/devops/building-and-running-custom-code-transformations-without-leaving-your-editor/

Custom code transformations are the work that no off-the-shelf migrator covers for you. Moving your services off an internal library, enforcing your team’s error-handling conventions, standardizing logging across your fleet of services: that work piles up on your backlog because general-purpose tools weren’t written with your codebase in mind.

AWS Transform custom tackles that kind of work. It’s an agentic AI service that lets you describe your own code transformations in natural language and run them across your codebase. With the Kiro power for AWS Transform, the AWS Transform agent skill, and the AWS Transform IDE plugin (VS Code and Open VSX), you can design and run those transformations from your editor. You can transform up to 3 repositories in parallel on your laptop, or fan out to hundreds of repositories in parallel on AWS Batch with AWS Fargate, without leaving the chat or IDE you already work in.

This post shows you what AWS Transform custom is, how to request a new transformation definition (TD) from chat, and how to run TDs through the power, skill, or IDE plugin. The authoring walkthrough focuses on the chat-driven request workflow. The agent drafts and publishes the TD on your behalf, so you won’t see raw TD syntax in this post.

What makes AWS Transform “custom”

AWS Transform ships with a catalog of out-of-the-box transformation definitions for common scenarios, including Java version upgrades, boto2 to boto3, AWS SDK migrations, framework transitions, and x86 to AWS Graviton. Those cover a lot of ground, but the real unlock is when you define your own.

A transformation definition is a reusable recipe that describes how to perform a transformation. With AWS Transform custom, you author TDs in natural language. A few examples of what that looks like in practice:

  • “Upgrade my codebase from C++11 to C++17”
  • “Replace calls to our deprecated internal auth-sdk-v1 with auth-sdk-v2, keeping the retry configuration intact.”
  • “Enforce our team’s error-handling standard: no bare except blocks, and every exception includes context.”
  • “Standardize our REST controllers to use our internal @TracedEndpoint annotation.”

Each one encodes something specific to your organization. Once you publish a custom TD to your AWS account, you can apply it to a matching repository, whether that’s one project or a hundred.

Three common ways to work with AWS Transform custom

You can pick the surface that fits how you already work. The power lives inside Kiro IDE, the skill plugs into your compatible agent, and the IDE plugin gives you a UI in VS Code or Open VSX-compatible IDEs. These three surfaces talk to the same underlying service and share your TDs, so you can mix and match across a team.

The Kiro power for AWS Transform brings the full AWS Transform workflow into Kiro IDE. You describe what you want in chat, and Kiro inspects your project, matches it against your available TDs, asks for the configuration it needs, and runs the transformation. Progress, artifacts, and diffs show up in your editor.

The AWS Transform agent skill follows the open Agent Skills standard. The same package works across more than 40 compatible agents, including Kiro CLI, Claude Code, Cursor, GitHub Copilot, Gemini CLI, and Windsurf. You get the same workflow you get from the Power, portable across the tools you already use.

The AWS Transform IDE plugin is for when you prefer a UI over chat. You can install it from the VS Code Marketplace and Open VSX. The plugin exposes AWS Transform custom features as first-class IDE actions, including browsing your published TDs and launching transformations.

Creating a custom TD right from chat

Historically, creating a custom TD meant dropping to the terminal and running the AWS Transform custom CLI to step through an interactive authoring session. That path still works and is a good fit for scripting. With the power, skill, or IDE plugin, you can do the same thing entirely in chat.

Tell your agent what you want, for example:

Create a custom AWS Transform custom TD that migrates our internal logger-v1 package to logger-v2. The new API uses logger.info(msg, context) instead of logger.log(level, msg). Keep existing log levels intact.

From there, the agent walks you through a short loop. It asks clarifying questions about the transformation’s scope and behavior, drafts the TD based on your description, lets you review and refine it, and then publishes it to your AWS account. After publishing, your TD is immediately available to the power, skill, and plugin. The next time you ask to run a transformation on a matching repo, your new TD shows up as a candidate.

The CLI path is still there if you prefer it. Run this in a new terminal:

atx

Then follow the interactive prompts.

Running your custom TDs

Once you have one or more TDs published, running them looks the same regardless of surface. When you ask Kiro to run a transformation, the Kiro Power walks through the following steps with you:

  1. Inspect your repositories. The agent reads pom.xml, package.json, requirements.txt, Dockerfiles, and similar config files to understand what it’s looking at.
  2. Match against your TDs. It compares your repos to your published TDs (custom and out-of-the-box) and presents a report showing which ones apply and why.
  3.  Collect the configuration it needs. Some TDs require inputs like a target version. The agent prompts you for those before it runs.
  4. Confirm the plan. Nothing executes until you approve.
  5. Execute and monitor. The agent launches the transformation through the AWS Transform CLI, streams progress, and opens artifacts (for example, plan, worklog, and validation summary) in your editor.
  6. Show results. Every change is a normal git commit you can review.

Local mode and remote mode: scale without the setup tax

Running locally, you can transform up to 3 repositories in parallel on your machine. That’s fine for one-off work, but it doesn’t scale to a real modernization campaign.

Remote mode is where scale comes in. It runs your transformations on AWS Batch with AWS Fargate, so you can fan out to hundreds of repositories in parallel. No local compute bottleneck, and no leaving your laptop running overnight.

The agent sets remote mode up for you. Ask to run in remote mode, and it provisions the AWS Batch compute environment, job queue, job definitions, IAM roles, and networking automatically. You don’t hand-write CloudFormation, and you don’t navigate the AWS console. Once the infrastructure is in place, you kick off a run the same way as local mode, and the agent streams progress back to your editor while Fargate does the heavy lifting.

Your inputs can be local paths, git URLs, or S3 locations, and the same applies to remote runs. Point the agent at a list of repos and let it go.

Getting started

The first time you use the power, skill, or IDE plugin, the agent walks you through setup. If you’d rather do it by hand, you need a few things in place first.

Install the power (Kiro IDE)

Before you install the power, make sure you have:

  1. AWS Command Line Interface (CLI) installed and configured with aws configure.
  2. AWS credentials with the AWSTransformCustomFullAccess managed policy (or at minimum, transform-custom:* permissions).
  3. macOS or Linux. Native Windows isn’t supported, so use WSL.

A straightforward way to install the power:

  1. Open Kiro IDE and open the Powers panel.
  2. Find AWS Transform in the list and install it.
  3. Open Kiro Chat, then select the Power and choose Try power.

To install from source instead:

  1. In the Powers panel, choose Add Custom Power, then Import power from GitHub.
  2. Paste: https://github.com/kirodotdev/powers/tree/main/aws-transform

Install the skill (any compatible agent)

Before you install the skill, install the AWS Transform custom CLI:

curl -fsSL https://transform-cli.awsstatic.com/install.sh | bash

Then add the skill to your agent:

npx skills add https://github.com/awslabs/agent-plugins/tree/main/plugins/aws-transform/skills/aws-transform  

Follow the prompts to finish the installation. You can also drop the skill folder into your agent’s skills directory manually, for example, .kiro/skills/ for Kiro CLI or .claude/skills/ for Claude Code.

Install the IDE plugin

The IDE plugin is published to two marketplaces:

  • VS Code Marketplace
  • Open VSX

Install it the same way you install any other extension in your editor.

Your first custom TD

Once you have a surface installed, try something like:

Create a custom AWS Transform transformation that [describe your transformation].

Then run it against a repo:

Use AWS Transform to run my new transformation on /path/to/my-project.

The agent walks you through creating the TD, modifying it, publishing it, and running it on your repos from start to finish.

Cleanup

If you ran any transformations in remote mode, once they complete, the agent will ask if you want to keep or clean up the remote mode resources deployed to your AWS account. To clean up, simply tell the agent that you want to clean up. The agent will then delete the resources that were created in your AWS account as a part of the initial setup for the remote mode transformations. To delete any user-managed transformation definition that you chose to publish to your registry, simply run atx in a terminal, ask to list all transformation definitions, find your recently published user-managed transformation definition, and ask to delete it from the registry.

Wrapping up: making your migrations faster

The value of AWS Transform custom is in the transformations only you can write, the ones that encode your organization’s libraries, conventions, and standards. The power, skill, and IDE plugin make both sides of that loop, authoring and running, feel native to your editor.

If you’ve been putting off your migrations because the tooling wasn’t there, now’s the time to take another look.

Learn more

About the author

DAVID

David Hasani

David Hasani is a Software Development Engineer at AWS, based out of the Bay Area. He works on AWS Transform custom and is excited about leveraging AI to solve the most critical business and technology challenges.

Prevent data exfiltration: AWS egress controls for cloud workloads

Post Syndicated from Meriem SMACHE original https://aws.amazon.com/blogs/security/prevent-data-exfiltration-aws-egress-controls-for-cloud-workloads/

When securing an Amazon Web Services (AWS) environment, teams naturally prioritize inbound controls, firewalls, WAFs, and access policies, because that’s where the most visible threats originate. Outbound traffic, on the other hand, tends to get less attention. It’s often left open by default to avoid breaking application dependencies and because the risk feels less immediate. But overlooking egress means missing a key layer of defense. Without visibility into what’s leaving your network, it’s harder to detect unintended data flows, whether from misconfigured services, overly broad permissions, or workloads with unauthorized access.

Real-world incidents highlight why egress controls deserve attention across both traditional cloud workloads and emerging AI-driven architectures.

In traditional cloud environments, application-level security issues remain a persistent threat. For example, when CVE-2025-55182 (React2Shell) was publicly disclosed in December 2025, multiple organized groups began exploitation attempts within hours, targeting unpatched React Server Components to achieve remote code execution. After a workload is accessed by an unauthorized party, they typically establish outbound command-and-control channels and begin exfiltrating data. Without egress controls in place, that outbound traffic can flow freely, and the unauthorized access might go unnoticed until a compliance audit, customer complaint, or incident notification forces discovery.

Agentic AI systems introduce a new dimension to this risk. The OWASP Top 10 for Agentic Applications identifies threats such as Agent Goal Hijack (ASI01), where unauthorized parties manipulate an autonomous agent’s objectives to silently exfiltrate data, and Unexpected Code Execution (ASI05), where an agent with unauthorized access generates and runs potentially damaging code that establishes reverse shells or transfers sensitive data to external endpoints. As organizations deploy AI agents with access to tools, APIs, and code interpreters, these agents become high-value targets, and their outbound network activity must be constrained with the same rigor as any other workload.

In both scenarios, the common thread is unauthorized outbound traffic. In this post, we show you how to implement layered egress detection and protection using AWS services working together to reduce unauthorized data transfer risk, whether the source is an application with unauthorized access or a manipulated AI agent.

Architecture overview

Figure 1: Hub-and-spoke egress control architecture

Figure 1: Hub-and-spoke egress control architecture

The following architecture, shown in Figure 1, illustrates one approach to implementing a hub-and-spoke network pattern for a multi-account AWS environment. Note that alternative designs might be appropriate depending on your organizational requirements and constraints.

Application workloads reside in spoke virtual private clouds (VPCs) that connect to an AWS Transit Gateway, which serves as the central hub for routing inter-VPC and internet-bound traffic while enforcing network segmentation through carefully crafted route tables. Spoke VPCs use VPC endpoints for secure AWS service access, keeping traffic within the AWS network where possible. VPC endpoint policies are applied as key data perimeter controls, restricting which principals can access AWS services and which resources can be accessed through these endpoints.

Internet-bound traffic is routed through a transit gateway-attached AWS Network Firewall, which inspects and filters outbound flows before they reach the internet. This centralized routing model scales horizontally by adding spoke VPCs without modifying the inspection infrastructure, making it well suited for organizations that have multiple AWS accounts.

It’s important to understand that Amazon Route 53 Resolver DNS Firewall must be deployed across your VPCs to filter DNS queries that resolve through the Route 53 VPC Resolver. (DNS queries sent directly to other DNS resolvers bypass it, but can be filtered with AWS Network Firewall.) The DNS firewall uses both managed and custom domain lists to filter DNS queries, blocking resolution of known unauthorized domains before any network connection is established.

Data perimeter controls are enforced at multiple layers: service control policies (SCPs) and resource control policies (RCPs) at the AWS Organizations level, VPC endpoint policies at the network level, and resource policies on individual services. AWS IAM Access Analyzer is deployed at the organization level to continuously detect publicly accessible or externally shared resources.

A detection layer comprising Amazon GuardDuty, AWS Security Hub, and IAM Access Analyzer provides continuous monitoring and threat detection. Findings are routed through an integration layer using Amazon EventBridge, which triggers AWS Lambda-based automated remediation and sends notifications using Amazon Simple Notification Service (Amazon SNS). This integration layer also feeds back into your network controls, automatically updating Network Firewall deny rules and DNS Firewall block lists based on detected threats.

Centralized observability is achieved through Amazon CloudWatch Logs and CloudWatch dashboards. Network Firewall flow logs and alert logs are collected centrally to support incident investigation and compliance reporting.

This architecture applies equally to traditional application workloads and AI-driven workloads. An AI agent running on Amazon Bedrock, for example, typically sits inside a spoke VPC. When that agent invokes an external API or attempts to reach the internet, its traffic follows the same path through Transit Gateway and Network Firewall as any Amazon Elastic Compute Cloud (Amazon EC2) or container workload. The agent doesn’t get a special lane out, it’s subject to the same domain allow-lists, the same DNS filtering, and the same data perimeter policies.

That said, agents often need outbound access to invoke external tools or third-party APIs as part of their normal operation, which makes allow-list design more nuanced. You will want to scope allowing domains tightly to the specific endpoints your agents legitimately need, rather than opening broad categories. Complementing these network-layer controls with application-layer guardrails such as Amazon Bedrock Guardrails—which can filter harmful content and detect prompt attacks before they reach the network layer—adds another layer of defense.

Preventive controls

The following preventive controls block data exfiltration before it occurs. Because they actively disrupt traffic, reserve them for activity that is confirmed or highly likely to be potentially damaging.

AWS Network Firewall

Consider this scenario: an unauthorized party compromises an EC2 instance in one of your spoke VPCs and attempts to exfiltrate sensitive data to an external server. Now consider an agentic AI scenario: an unauthorized party uses prompt injection to hijack an AI agent’s goal (OWASP ASI01), redirecting it to exfiltrate training data to an external endpoint. Network Firewall is designed to block this attempt because the unauthorized destination isn’t on the approved domain allow-list—the same control that stops an EC2 instance with unauthorized access— also stops a manipulated AI agent.

Without centralized egress inspection, that traffic flows directly to the internet through a NAT gateway. Network Firewall prevents this by providing centralized, Layers 3–7 deep packet inspection with advanced threat intelligence capabilities, including IP address, port, and protocol filtering; plus packet content inspection using Suricata-compatible rules.

In this architecture, Transit Gateway funnels internet-bound traffic from multiple spoke VPCs through Network Firewall for centralized inspection. The firewall endpoint becomes the target for 0.0.0.0/0 routes, routing outbound internet traffic for inspection before reaching NAT gateways for address translation. In both scenarios, Network Firewall blocks the exfiltration attempt at the network layer before data leaves your environment. Its key capabilities include:

  • Domain name filtering: Block traffic to unauthorized destinations (such as a command-and-control server at *.untrusted-domain.com)
  • IP and port rules: Define explicit allow-lists for external IPs your applications truly need, blocking everything else
  • Domain category filtering: Block entire categories of domains that your workloads should never communicate with
  • IDS and IPS: Detect and block known attack patterns in outbound traffic using Suricata-compatible rules
  • Port and protocol enforcement: Help ensure only expected protocols use their designated ports (for example, only HTTPS on TCP port 443), preventing protocol tunneling
  • Geographic IP filtering: Block outbound traffic to geographic regions where your organization has no business relationships
  • TLS decryption: Inspect encrypted traffic to detect exfiltration attempts hidden within HTTPS connections
  • Threat intelligence integration: Use managed threat intelligence (such as active threat defense that uses the Amazon threat intelligence system MadPot) feeds or custom Suricata rules to detect unexpected patterns
  • Automatic scaling: Handles up to 100 Gbps per Availability Zone

For multi-account environments, AWS Firewall Manager can centrally deploy and manage Network Firewall across your organization’s accounts, helping maintain consistent egress rules everywhere. Additionally, AWS Network Firewall Proxy (in preview) offers explicit proxy capabilities with granular HTTP/HTTPS filtering—including URL path and HTTP method-level controls—for workloads that require application-layer inspection of outbound web traffic.

Route 53 Resolver DNS Firewall

DNS queries made through Route 53 VPC Resolver don’t pass through the outbound network path inspected by Network Firewall or third-party firewalls. Unauthorized parties can take advantage of this by encoding sensitive data within DNS queries to external servers, a technique known as DNS tunneling. This risk extends to agentic AI workloads. An agent with code execution capabilities (OWASP ASI05) could be tricked into running a script that encodes sensitive data (like customer records, model weights, API keys) into DNS queries directed at an externally controlled nameserver. DNS Firewall is designed to block these queries regardless of whether they originate from a traditional workload or an AI agent, because the filtering happens at the resolver level before any connection is established.

Because DNS traffic is essential for normal operations and often overlooked in security architectures, it represents a common unauthorized data exfiltration channel. Route 53 Resolver DNS Firewall closes this gap by filtering and potentially blocking outbound DNS queries from your VPCs. Its core capabilities consist of:

  • Block unauthorized domains: AWS provides managed domain lists, including an Aggregate Threat List covering malware, ransomware, botnet, spyware, and DNS tunneling
  • Enforce allow-lists: Permit only queries to approved domains, blocking everything else
  • DNS Firewall Advanced features: AI and machine learning (AI/ML)-backed detection of DNS tunneling, Domain Generation Algorithms (DGAs), and dictionary DGAs

Configuration is straightforward: Create rule groups with domain match lists and actions (block, allow, and alert), then associate them with your VPCs. The DNS resolver applies these rules to every DNS query made from instances in the VPC through Route 53 Resolver. This prevents unauthorized parties from using DNS tunneling to exfiltrate data, a technique that completely bypasses inspection by firewalls in the egress VPC.

For a deeper look at the risks associated with DNS exfiltration and DNS Firewall Advanced capabilities, see Protect against advanced DNS threats with Amazon Route 53 Resolver DNS Firewall.

Data perimeters

A data perimeter is a set of preventive guardrails that allow only your trusted identities to access trusted resources from expected networks. While the preceding controls secure the network paths out of your environment, data perimeters secure the API-level paths, helping to ensure that even if an unauthorized party gains access to valid credentials, they can’t use AWS service APIs to move data to resources outside your organization.

This comprehensive approach uses three primary AWS capabilities working together:

  1. Service control policies (SCPs): Organization-wide preventive controls that restrict what identities can do. In the context of egress protection, SCPs can prevent users from creating resources that bypass your egress controls (for example, preventing the creation of VPCs without DNS Firewall associations or blocking the use of services that could establish alternative outbound paths).
  2. Resource control policies (RCPs): Controls that restrict API access to your resources. While RCPs aren’t directly egress controls, they act as a complementary layer. For example, they can block attempts to access your Amazon Simple Storage Service (Amazon S3) buckets from outside your organization at the resource level.
  3. VPC endpoint policies: VPC endpoints enable private communication with AWS services without traffic going through the internet. VPC endpoint policies are resource-based AWS Identity and Access Management (IAM) policies that govern what can be accessed through that endpoint. This is where data perimeters most directly function as an egress control.

Consider the following VPC endpoint policy that restricts Amazon S3 access through the endpoint to only S3 buckets within your organization, directly preventing an insider or a workload with unauthorized access from copying data to an external S3 bucket:

{
  "Statement": [{
    "Sid": "DenyAccessToNonOrgBuckets",
    "Effect": "Deny",
    "Principal": "*",
    "Action": "s3:*",
    "Resource": "*",
    "Condition": {
      "StringNotEqualsIfExists": {
        "aws:ResourceOrgID": "<my-org-id>"
      }
    }
  }]
}

This policy is designed to deny any Amazon S3 operation through this VPC endpoint unless the target S3 bucket belongs to your organization. Without this control, a workload with unauthorized access could use aws s3 cp to copy sensitive data to an externally controlled bucket in a different AWS account.

Data perimeter policies don’t grant new permissions, they narrow what’s accessible by establishing guardrails, acting as a second authorization layer. By implementing these perimeters using IAM condition keys like aws:PrincipalOrgID, aws:ResourceOrgID, aws:SourceVpc, and aws:SourceVpce, you create layered permissions guardrails that help prevent unintended access patterns and configuration errors.

For more information on implementing perimeter controls, explore the Building a Data Perimeter AWS whitepaper.

Detective controls

The following detective controls surface data exfiltration attempts after they occur. Because they observe rather than disrupt traffic, you can apply them broadly to flag unexpected activity for investigation. Use the findings to identify recurring unauthorized patterns that can graduate into preventive controls.

Amazon GuardDuty: Detective control for egress threats

GuardDuty serves as your critical detection layer for egress protection, continuously monitoring for outbound threats that evade or take advantage of your preventive controls. GuardDuty identifies behavioral anomalies and attack patterns that indicate active data exfiltration attempts. Its egress-focused detection capabilities include:

  • DNS-based data exfiltration detection: The Trojan:EC2/DNSDataExfiltration finding alerts when EC2 instances are transferring data through DNS channels. GuardDuty also identifies queries to DGA domains commonly used for command-and-control communication.
  • Known malicious actor detection: Exfiltration:S3/MaliciousIPCaller triggers when Amazon S3 data APIs like GetObject or CopyObject are invoked from IP addresses on AWS threat intelligence feeds, signaling active data extraction attempts.
  • Multi-step attack sequence correlation: GuardDuty Extended Threat Detection correlates multiple unexpected events to identify multi-stage exfiltration campaigns. For example, AttackSequence: S3/CompromisedData detects when unauthorized parties modify S3 bucket policies to broaden access and then systematically extract data using stolen credentials.

GuardDuty findings serve dual purposes in your egress strategy. Alerts about attempted exfiltration that failed confirm your preventive layers (Network Firewall, DNS Firewall, and data perimeters) are functioning effectively: the threat was detected because it progressed far enough to trigger behavioral analysis, but your controls blocked the actual data loss. Conversely, findings indicating successful exfiltration trigger immediate incident response workflows, enabling you to contain active incidents, revoke stolen credentials, and quarantine affected resources before significant damage occurs.

Integrate GuardDuty with Security Hub for centralized correlation across your security services and implement automated response through EventBridge and Lambda functions to enable real-time containment when high-severity exfiltration findings occur.

IAM Access Analyzer

IAM Access Analyzer helps identify potential data exfiltration paths by detecting resources accessible from outside your AWS account or organization. It uses automated reasoning technology to analyze resource-based policies and identify which of your resources can be accessed by external entities (principals outside your zone of trust), continuously monitoring public and cross-account access.

External access analyzers identify resources shared with external principals (such as other AWS accounts or public access). For example, when an S3 bucket is configured to allow access outside your zone of trust through bucket policies, ACLs, or access points, IAM Access Analyzer generates a finding with details about the access path, including the external principal and the level of access granted. Security teams can respond by taking immediate action to remove unintended access or by setting up automated notifications through EventBridge to engage development teams for remediation.

AWS Security Hub

Security Hub exposure findings provide a comprehensive view of potential security risks by correlating data from multiple AWS security services. These findings identify when resources might be vulnerable to data exfiltration by integrating intelligence from GuardDuty (for threat detection), Amazon Inspector (for vulnerability assessment), Security Hub CSPM (for configuration compliance), and Amazon Macie (for sensitive data discovery). For example, it can identify when a publicly exposed S3 bucket contains sensitive data and isn’t encrypted at rest, flagging it as a potential data exfiltration risk that requires immediate attention.

AWS Shield network security director (in preview) complements Security Hub by discovering and analyzing your network topology to identify resources with unrestricted outbound internet access, helping you detect potential egress blind spots across your environment.

Egress security strategy

You don’t need to implement all these controls at once. The following phased approach lets you build your egress security posture incrementally, at a pace that matches your organization’s operational maturity and risk tolerance.

  • Phase 1 – Quick wins: Enable Route 53 DNS Firewall across your VPCs to close the DNS exfiltration gap. Enable GuardDuty across your accounts for baseline threat detection.
  • Phase 2 – Foundational: Deploy organization-wide data perimeters (SCPs, RCPs, and VPC endpoint policies). Deploy Network Firewall as a transit gateway-attached firewall.
  • Phase 3 – Efficient: Enable IAM Access Analyzer for continuous external access detection. Implement automated remediation through EventBridge and Lambda to update firewall rules in real time. Centralize findings in Security Hub with automated alerting.

Conclusion

Egress security isn’t a single control—it’s a layered strategy. Start by assessing your current posture across network filtering, DNS security, data perimeters, and detective controls. Identify the gaps, then follow the phased approach outlined in this post to close them incrementally. Regular testing through simulated exfiltration attempts validates that your controls work effectively. These controls apply with equal force to agentic AI workloads, where manipulated agents can become unintended exfiltration vectors. Put egress under control and turn your outbound blind spots into monitored checkpoints.

If you have feedback about this post, submit comments in the Comments section below.


Merriem-SMACHE

Meriem SMACHE

Meriem is a Security Specialist Solutions Architect at AWS, supporting customers in the design and deployment of resilient cloud and AI solutions, from generative AI workloads to fully autonomous agentic systems, that meet their regulatory requirements and security needs.

Maxim Raya

Maxim Raya

Maxim is a Security Specialist Solutions Architect at AWS. In this role, he helps clients accelerate their cloud transformation by increasing their confidence in the security and compliance of their AWS environments.

Feature Flag Orchestration with AWS DevOps Agent and LaunchDarkly

Post Syndicated from Greg Eppel original https://aws.amazon.com/blogs/devops/feature-flag-orchestration-with-aws-devops-agent-and-launchdarkly/

Introduction

Organizations that use feature flags alongside incident response tooling often connect the two manually. When an outage occurs, engineers must identify which flags are relevant, decide whether to disable them, and coordinate the change across teams. This manual process adds latency at the moment it matters most.

You can use AWS DevOps Agent and its MCP server feature to connect to LaunchDarkly’s hosted MCP server, enabling feature flag recommendations during both proactive deployment review and reactive incident response workflows. Once connected, DevOps Agent can query flag state, read targeting rules, and surface recommendations directly within the workflows where engineers make decisions.

This post walks through two primary use cases:

  1. Pre-deployment review where the release management capabilities in AWS DevOps Agent evaluate changes and a DevOps Agent Skill recommends feature flag coverage before code ships.
  2. Incident response where DevOps Agent queries LaunchDarkly flag state via MCP and recommends containment actions during active incidents.

We also cover the connection architecture, a reusable DevOps Agent Skill for pre-deployment flag validation, and links to get started.

Defense: Release Management and Proactive Flag Recommendations

Five-step sequence diagram of the pre-deployment review workflow: PR Submitted, DevOps Agent Readiness Review Analyzes PR, Flag Gate Skill recommends a LaunchDarkly flag, Recommendation Surfaced, Developer Reviews.

Figure 1: DevOps Agent’s readiness review identifies high-risk PRs and recommends LaunchDarkly feature flag coverage before code ships.

The release management capabilities (now in public preview) in AWS DevOps Agent evaluate code changes before they ship to production.

It performs functional testing in an AWS-managed verification environment, assesses risks to cross-codebase dependencies, evaluates adherence to your organization’s standards and best practices, and mathematically verifies that access control configurations in CloudFormation do not deviate from Well-Architected best practices.

AWS DevOps Agent is designed to be extended and customized to fit your tools, standards, and practices. Using the product’s primitives, you can add Skills that enhance its capabilities. For example, when a high-risk change is identified, a custom Skill can evaluate whether the change has adequate feature flag coverage, operating on deployment metadata and code analysis to identify gaps and surface a recommendation to the developer, such as recommending feature flags with LaunchDarkly when needed.

What the Skill Evaluates

The release readiness flag Skill classifies code changes into risk tiers (Critical, High, Moderate) based on what’s being modified — payments, authentication, database schemas, third-party integrations, new API endpoints, performance-sensitive paths, and more — and recommends feature flags proportional to the risk level.

Screenshot of the AWS DevOps Agent Knowledge panel on the Skills tab, showing a custom skill named "high-risk-feature-flag-recommendations" with a description that reads "Evaluates code changes during release readiness reviews to identify high-risk modifications and recommends wrapping them in LaunchDarkly feature flags for safer rollouts."

Figure 2: The high-risk-feature-flag-recommendations Skill configured in AWS DevOps Agent’s Knowledge panel.

What the Recommendation Includes

When the Skill identifies a gap, it surfaces a recommendation containing:

  • Risk context: Why the change is flagged as high-risk (e.g., “This deployment modifies payment authorization logic across 3 downstream services with no existing rollback mechanism.”)
  • Suggested flag configuration: A proposed LaunchDarkly flag key, variations, and default targeting rules aligned with the deployment plan.
  • Rollout strategy: A recommended phased rollout (e.g., internal users first, then 5% of traffic, then full rollout) that matches the risk profile.
  • Kill-switch behavior: What happens when the flag is turned off — the fallback code path, cleanup considerations, and data consistency implications.

Example Scenario

Consider a team deploying an update to a tax calculation service. The change modifies the tax rate computation logic, affecting all order totals across multiple regions. AWS DevOps Agent evaluates the deployment and classifies it as high-risk. The pre-deployment flag gate Skill then identifies:

  • The change touches critical-path tax calculation code.
  • No feature flag wraps the new computation behavior.
  • The blast radius covers all active checkout sessions.

The Skill surfaces a recommendation: “This deployment modifies tax calculation logic with no existing feature flag coverage. Recommend wrapping the new tax computation in a LaunchDarkly flag (tax-calculation-v2) with a phased rollout targeting internal test accounts first, followed by 5% of production traffic.” 

The developer can then action the recommendation, creating the flag in LaunchDarkly, adjusting the suggested configuration to fit their rollout plan, or noting the justification for proceeding without one as part of the deployment record.

Screenshot of the AWS DevOps Agent Report tab showing a policy violation titled "Checkout pricing changes deployed without a LaunchDarkly feature flag." The report includes risk context, evidence from a repo grep showing no existing flag, a suggested fix with sample Node.js code using the LaunchDarkly SDK, and a recommended phased rollout strategy.

Figure 3: AWS DevOps Agent release management report identifying checkout pricing changes deployed without LaunchDarkly feature flag coverage, including a suggested fix with sample code.

Closing the Loop with Kiro IDE

DevOps Agent’s release management capabilities identify when a deployment needs feature flag coverage. Paired with Kiro IDE, this recommendation becomes actionable without leaving the development workflow.

Kiro connects to LaunchDarkly’s MCP server directly, providing flag integration capabilities during development. When a developer builds a new feature in Kiro, the IDE can query LaunchDarkly via MCP to check whether a flag already exists for that feature and generate code with the flag evaluation built in from the start.

Together, this creates one continuous flow: DevOps Agent identifies the risk and recommends flag coverage → the developer, working in Kiro, generates the flag and wraps the code in a single action → the deployment ships with coverage already in place. No context-switching between tools, no manual flag creation in a separate console.

Developers can also use Kiro’s flag integration independently during feature development, even before a deployment triggers a release management review. The two operate as layered coverage: if Kiro catches it during development, DevOps Agent validates the targeting rules match the rollout plan at deployment time. If the developer bypasses Kiro or uses a different toolchain, DevOps Agent still identifies the gap.

Offense: Flag Recommendations During Incident Response

During an active incident, speed of containment directly affects customer impact. DevOps Agent participates in incident response workflows by querying LaunchDarkly to understand current flag state, then recommending containment actions based on what it finds.

Sequence diagram: Incident Detected, DevOps Agent correlates with flag change, queries LaunchDarkly via MCP (value changed to 30ms from 2000ms), recommends reverting to 2000ms, engineer confirms action.

Figure 4: DevOps Agent identifies a flag change (30ms from 2000ms) as the probable cause, queries LaunchDarkly for state, and recommends reverting the value.

When you detect an incident, DevOps Agent correlates the affected service with recent deployments. It queries LaunchDarkly to identify feature flags associated with those deployments and their current state (enabled, targeting rules, rollout percentage). If a relevant flag is enabled, the agent recommends disabling it as a containment option before suggesting a full rollback.

Flag-based containment provides an alternative containment option that can help reduce the time to resolution. Disabling a flag may return behavior to the previous state, which can be faster than a full deployment rollback in some scenarios

Example Scenario

An alert fires indicating sustained 5XX errors on the bot-service. The on-call engineer engages DevOps Agent, which:

  1. Correlates the HTTP 503 errors with a LaunchDarkly feature flag change: bot-mutation-orchestration-timeout-ms was changed from the default 2000ms to 30ms (the “low latency” variation), applied to all traffic.
  2. Identifies that the 30ms timeout budget is insufficient for inter-service HTTP calls during bot creation and deletion orchestration, which require DynamoDB reads/writes plus IoT Core calls, causing ReadTimeout exceptions.
  3. Recommends reverting the bot-mutation-orchestration-timeout-ms flag to its default variation (2000ms) as the containment action, noting this will restore sufficient timeout budget without requiring a code deployment.

The engineer reviews the recommendation, updates the flag variation in LaunchDarkly, and the error rate returns to baseline within minutes.

Screenshot of the AWS DevOps Agent Root cause tab showing an investigation summary. The Impact section reports bot-service ALB returning sustained 5XX errors since 18:52Z with 136 errors in 10 minutes. The Root causes section, highlighted with a red border, identifies that the LaunchDarkly feature flag "bot-mutation-orchestration-timeout-ms" was changed to 30ms from the default 2000ms, causing ReadTimeout exceptions.

Figure 5: AWS DevOps Agent investigation summary identifying a LaunchDarkly feature flag timeout change as the root cause of sustained 5XX errors

Step-by-Step Mitigation Plans

When DevOps Agent identifies a root cause, it generates a structured mitigation plan with concrete, executable steps. Rather than a generic recommendation, the agent provides:

  1. Prepare — Document the current error baseline (with ready-to-run CLI commands, e.g., CloudWatch get-metric-statistics) and confirm the problematic configuration is still active before making changes.
  2. Execute — Revert the specific change (in this case, reverting the LaunchDarkly feature flag bot-mutation-orchestration-timeout-ms from 30ms back to the 2000ms default) with clear instructions on which variation to target.
  3. Verify — Validate that error rates return to baseline after the change, confirming the mitigation was effective.

Each step includes sub-steps with specific commands, API paths, and success criteria — giving the on-call engineer a clear, auditable runbook rather than a vague recommendation.

Screenshot of the AWS DevOps Agent Mitigation plan tab showing a plan titled "Revert LaunchDarkly feature flag 'bot-mutation-orchestration-timeout-ms' from 30ms to 2000ms default value." The plan includes Step 1: Prepare, with sub-steps to document the current 5XX error baseline using an AWS CLI command and confirm the flag is still serving the problematic 30ms value.

Figure 6: Structured mitigation plan generated by AWS DevOps Agent with executable steps to revert the feature flag and verify resolution.

Below, the LaunchDarkly targeting configuration shows the bot-mutation-orchestration-timeout-ms flag with its available variations. During the incident, the engineer reverted from the “low latency” variation back to “default” to restore the 2000ms timeout budget.

Screenshot of the LaunchDarkly console showing the targeting configuration for the "bot-mutation-orchestration-timeout-ms" flag in the Production environment. The flag is set to Off, serving the "default" variation to all traffic. A dropdown menu displays the available variations: 1, 0, default (selected), low latency, and moderate.

Figure 7: LaunchDarkly targeting configuration for the bot-mutation-orchestration-timeout-ms flag showing available variations including the default and low latency values.

Connecting to LaunchDarkly via MCP

As described in the introduction, DevOps Agent uses its MCP server feature to connect to LaunchDarkly’s hosted MCP server. This section covers the architecture and setup steps.

LaunchDarkly’s MCP server exposes flag management operations as agent-callable tools through the Model Context Protocol (MCP) standard. DevOps Agent connects as a client, giving it the ability to query flag state, read targeting rules, and list flags by project or environment without custom integration code.

Architecture

The connection follows this flow:

  1. DevOps Agent identifies a need for flag-related context (e.g., during incident response).
  2. DevOps Agent calls LaunchDarkly’s hosted MCP server using standardized MCP tool definitions.
  3. LaunchDarkly MCP Server translates the request into LaunchDarkly API calls and returns structured responses (flag state, targeting rules, rollout percentages).
  4. DevOps Agent uses the response to formulate recommendations presented to the engineer.

Registration and Configuration

To set up the connection:

  1. Register LaunchDarkly’s hosted MCP server endpoint with DevOps Agent.
  2. Configure authentication credentials (LaunchDarkly API key with appropriate scopes).
  3. Validate connectivity by running a test flag query.

For the full setup walkthrough, including detailed configuration steps and permissions requirements, refer to LaunchDarkly’s companion blog post (link placeholder).

The same LaunchDarkly MCP server connection is available in Kiro IDE for flag-aware code generation during development; see the Defense section above for how Kiro completes the pre-deployment workflow.

Example Skill: High-Risk Feature Flag Recommendations

AWS DevOps Agent Skills are modular instruction sets that extend the agent’s capabilities with specialized domain knowledge and investigation methodologies tailored to your infrastructure and operational workflows. AWS DevOps Agent supports a subset of the Agent Skills specification. The format is flexible, but this example is structured into the following sections:

  • Risk Classification Criteria — defines what constitutes Critical, High, and Moderate risk changes
  • Feature Flag Recommendation Format — specifies the output structure: flag name, flag type, targeting strategy, and kill switch guidance
  • Example Recommendations — provides reference examples so the agent produces consistent, actionable output
  • Integration Notes — describes how recommendations surface during release readiness reviews
  • What NOT to Flag — explicitly scopes out low-risk changes to reduce noise

Below is the full Skill used in this example:


# High-Risk Code Feature Flag Recommendations

When performing a release readiness review, use this skill to identify high-risk code changes and recommend LaunchDarkly feature flags for safer, controlled rollouts.

## Risk Classification Criteria

Evaluate code changes against these risk categories:

### Critical Risk (Always recommend feature flag)
- **Payment/billing logic** — any changes to checkout, payment processing, subscription handling, or pricing calculations
- **Authentication/authorization** — login flows, session management, permission checks, OAuth/SSO integrations
- **Database schema changes** — migrations, new columns, index changes, especially on high-traffic tables
- **Data deletion or mutation** — bulk updates, cascading deletes, data transformations
- **Third-party API integrations** — new external service dependencies or changes to existing integrations
- **Core business logic** — order processing, inventory management, user registration flows

### High Risk (Strongly recommend feature flag)
- **New API endpoints** — especially public-facing or partner APIs
- **Performance-sensitive paths** — changes to hot paths, caching logic, query optimizations
- **Feature rewrites** — replacing existing functionality with new implementations
- **Concurrency changes** — threading, async processing, queue handling modifications
- **Configuration changes** — environment variables, feature toggles, service endpoints

### Moderate Risk (Consider feature flag)
- **UI changes to critical flows** — checkout pages, login screens, dashboard views
- **Logging/monitoring changes** — new metrics, log format changes, tracing modifications
- **Error handling changes** — exception handling, retry logic, fallback behaviors

## Feature Flag Recommendation Format

When recommending a feature flag, provide:

### 1. Flag Name
Use a descriptive, lowercase, hyphenated name:
- `enable-new-payment-processor`
- `use-v2-auth-flow`
- `rollout-order-service-refactor`

### 2. Flag Type
Recommend the appropriate LaunchDarkly flag type:
- **Boolean** — simple on/off for feature enablement
- **Multivariate** — when you need multiple variations (A/B testing, gradual migrations)
- **Number/String** — for configuration values that might need adjustment

### 3. Targeting Strategy
Recommend an appropriate rollout strategy:
- **Percentage rollout** — start at 1-5%, monitor, then increase (default for most changes)
- **User segment targeting** — internal users first, then beta users, then general availability
- **Environment targeting** — enable in staging/canary before production

### 4. Kill Switch Guidance
Explain what happens when the flag is turned off:
- What code path executes when disabled
- Any cleanup or rollback considerations
- Data consistency implications

## Example Recommendations

### Example 1: Payment Processing Change

**Code Change:** Refactored payment gateway integration to support new processor

**Recommendation:**
```CRITICAL RISK: Payment processing changes detected

Recommend wrapping in LaunchDarkly feature flag:
- Flag name: `enable-stripe-v2-integration`
- Flag type: Boolean
- Default: OFF (use existing payment flow)

Rollout strategy:
1. Enable for internal test accounts first
2. Expand to 1% of production traffic
3. Monitor payment success rates and error logs
4. Gradually increase to 100% over 1-2 weeks

Kill switch behavior: Reverts to existing payment processor immediately. 
In-flight transactions will complete with their original processor.
```

### Example 2: New API Endpoint

**Code Change:** Added new `/api/v2/orders` endpoint with different response format

**Recommendation:**
```HIGH RISK: New API endpoint with breaking response format

Recommend wrapping in LaunchDarkly feature flag:
- Flag name: `enable-orders-api-v2`
- Flag type: Boolean
- Default: OFF (return v1 format)

Rollout strategy:
1. Enable for specific API clients by client_id targeting
2. Coordinate with consuming teams before enabling
3. Run both versions in parallel during migration period

Kill switch behavior: Returns v1 response format. Ensure v1 
serialization logic remains in codebase until flag is permanent.
```

### Example 3: Database Migration

**Code Change:** Adding new index to high-traffic `orders` table

**Recommendation:**
```CRITICAL RISK: Database schema change on high-traffic table

Recommend wrapping dependent code in LaunchDarkly feature flag:
- Flag name: `use-orders-status-index`
- Flag type: Boolean  
- Default: OFF (use existing query patterns)

Rollout strategy:
1. Deploy migration to create index (can be done independently)
2. Deploy code that uses new index behind flag
3. Enable flag in staging, verify query performance
4. Enable in production during low-traffic window
5. Monitor query latency and database load

Kill switch behavior: Queries fall back to non-indexed path.
May see temporary performance degradation but no data loss.
```

## Integration Notes

When the release readiness review identifies high-risk changes:

1. **Surface the risk level** clearly in the review summary
2. **Provide the flag recommendation** with copy-paste ready configuration
3. **Explain the rollout strategy** appropriate for the risk level
4. **Document the kill switch behavior** so operators know what to expect

## What NOT to Flag

Not every change needs a feature flag. Avoid recommending flags for:
- Pure refactoring with no behavior change
- Test file additions or modifications
- Documentation updates
- Dependency version bumps (unless major version with breaking changes)
- Code formatting or linting fixes

Activating the Skill

DevOps Agent loads Skill metadata at the start of each workflow and loads the full Skill content when it determines relevance. To ensure the feature flag Skill is consistently applied during release readiness reviews, add a directive to your DevOps Agent Instructions (Agent.md), which is loaded in full at the start of every session:

“When performing release readiness reviews, always load and apply the high-risk-feature-flag-recommendations skill to evaluate code changes for risk and recommend LaunchDarkly feature flags where appropriate.”

This guarantees the agent loads and applies the Skill for every release readiness review rather than relying on relevance detection to surface it.

Getting Started

To begin using feature flag orchestration with AWS DevOps Agent and LaunchDarkly:

  1. Enable AWS DevOps Agent in your AWS account to start building Skills and connecting MCP servers
  2. Set up the LaunchDarkly MCP server: Follow the LaunchDarkly MCP server documentation for installation and configuration instructions.
  3. Read the companion post: LaunchDarkly’s blog post explores why feature flags are essential infrastructure for SRE agents and how the LaunchDarkly MCP Server connects to AWS DevOps Agent for pre-deployment review and incident response workflows.

Conclusion

Feature flag orchestration with AWS DevOps Agent and LaunchDarkly reduces the manual coordination required during both deployment review and incident response. A DevOps Agent Skill surfaces flag recommendations before high-risk changes ship, and during incidents, the agent queries LaunchDarkly to recommend flag-based containment, providing faster resolution with less disruption than full rollbacks.

For developers using Kiro IDE, the same LaunchDarkly MCP server enables flag-aware code generation during development, shifting flag coverage left to the point of authorship. Together, these workflows provide layered coverage: individual developers build with flags, DevOps Agent’s release management capabilities validate coverage at deployment time, and DevOps Agent uses flag state during incident response.

Authors

Greg Eppel

Greg Eppel is a Principal Specialist for DevOps Agent and has spent the last several years focused on Cloud Operations and helping AWS customers on their cloud journey.

Carl Caum

Carl Caum is a Senior Product Manager for DevOps Agent focused on accelerating safe software delivery through agentic solutions.

Supercharge your cloud operations with the Kiro power for AWS DevOps Agent

Post Syndicated from Shashiraj Jeripotula original https://aws.amazon.com/blogs/devops/supercharge-your-cloud-operations-with-the-kiro-power-for-aws-devops-agent/

When an alarm fires at 2 AM, the first thing most engineers do is grep logs, check recent deployments, and trace code paths. However, the context they need — metrics, traces, topology, configurations — lives in a separate browser tabs and applications. What if your IDE could bring that cloud intelligence directly to your code, understand the full picture, and help you fix the issue end-to-end? Introducing, The Kiro power for AWS DevOps Agent removes that context switching by connecting your IDE directly to the AWS DevOps Agent, so you can investigate incidents, identify root causes, and generate fixes, all from the same place you write code.

This post is for developers and operators who develop applications using Kiro and want to troubleshoot production issues faster without leaving their editor. We’ll walk through how the power works, what it can do, and a step-by-step example of resolving a real incident.

The Kiro power for AWS DevOps Agent connects Kiro, the AI-powered IDE from Amazon, to the AWS DevOps Agent. It brings the production intelligence and release management in AWS DevOps Agent directly into your development environment — where you already plan, architect, debug, and ship code.

With this power installed, you can review your changes for production risks, investigate production incidents, optimize costs, review architecture, map service topology, and generate remediation code — all through natural language conversation, enhanced with the local context of your workspace.

Challenges in cloud operations today

Operating modern cloud applications means navigating a maze of interconnected services. A single user-facing error might require tracing through Amazon Elastic Container Service (Amazon ECS) tasks, Application Load Balancers, AWS Lambda functions, Amazon DynamoDB tables, and dozens of Amazon CloudWatch metric dimensions. Operators face persistent challenges:

  • Context switching — Investigating an incident requires jumping between the IDE, the AWS Management Console, log viewers, trace explorers, and documentation. Each switch costs time and breaks concentration during high-pressure incidents.
  • Siloed knowledge — Understanding which metrics matter, which services depend on each other, and what “normal” looks like for a given application often lives in runbooks that are outdated or in the heads of senior engineers. New team members face a steep learning curve.
  • Remediation gap — Even after identifying a root cause, translating findings into a working fix — an AWS CloudFormation parameter change, a scaling policy update, or an AWS Identity and Access Management (IAM) policy correction — requires switching contexts again and manually applying changes.
    These challenges compound when teams operate across multiple AWS accounts and environments. Kiro powers address these challenges by bringing operational intelligence directly into the IDE where developers already work.

Challenges in modern software delivery

AI coding agents have changed how fast code gets written, but the code review, testing, and pipeline processes that move code to production were designed for human pace and haven’t kept up. Teams face two persistent challenges:

  • Review capacity — AI-assisted development produces changes faster than human reviewers can evaluate them. Changes that don’t adhere to internal standards, dependency breaks, and access-control gaps that would have been caught by human reviews can slip through at machine pace.
  • Invisible dependencies — Applications span multiple repositories, shared infrastructure, and cross-team API contracts. A parameter rename in one repository silently breaks downstream consumers, and no single reviewer holds the full dependency graph in their head.

Faster code generation without corresponding delivery automation simply moves the bottleneck downstream. The Kiro power for AWS DevOps Agent addresses this by bringing release management intelligence into the IDE so you can review changes for production risks and run exploratory release testing of your web and API applications. Any issues can be immediately mitigated before you even push your code changes.

What are Kiro powers?

A Kiro power is a curated package that gives Kiro specialized capabilities in a specific domain, in this case, AWS operations. When installed, the power provides Kiro with tool connections to your AWS environment, domain-specific knowledge (best practices, error recovery patterns), and instructions for routing your requests to the right workflow. Critically, the power combines your local workspace context (code, git history, configuration files) with cloud-side intelligence (metrics, topology, deployment history) — so Kiro understands both what your code does and how your infrastructure behaves. For a deeper look at the powers framework, see Getting started with Kiro powers

Each power typically includes:

  • MCP server configuration — Connects Kiro to external tools and data through the Model Context Protocol, providing read and write access to cloud resources
  • Steering files — Domain-specific instructions that teach Kiro how to route intents, choose the right workflow, and handle edge cases
  • Contextual knowledge — Domain-specific guidance captured in markdown spec files and lifecycle hooks that encode best practices, common patterns, and error recovery strategies (as described in the blog, Introducing powers).

The Kiro power for AWS DevOps Agent

The Kiro power for AWS DevOps Agent packages the full capabilities of AWS DevOps Agent into a single install for Kiro. Once enabled, Kiro gains the ability to converse with a specialized AI agent that has deep knowledge of your AWS infrastructure, your operational history, and AWS best practices.

You can do the following with this power:

  • Investigate incidents — Describe the symptoms in natural language (“ECS tasks are failing with OOM errors on my-service”) and Kiro orchestrates a deep investigation across CloudWatch metrics, AWS X-Ray traces, Amazon ECS task events, and recent deployments to identify the root cause.
  • Optimize costs — Ask “What cost savings are available for my ECS services?” and receive specific, data-backed recommendations with estimated monthly savings based on actual utilization metrics from your account.
  • Review architecture — Request a topology map or security audit of your services. The agent queries your infrastructure and returns findings with actionable improvement suggestions.
  • Chat across agent spaces — Operate across multiple AWS DevOps Agent agent spaces from a single Kiro session using AWS SigV4. Each agent space can represent a different team, application, or AWS account — and you can switch between them naturally.
  • Generate remediation code — After identifying a root cause, Kiro can generate the fix directly in your workspace. Because it has access to both the investigation findings and your local code, the remediation is specific to your application, not generic boilerplate.
  • Run a release readiness review — After finishing a batch of code changes, have the DevOps Agent review the changes for dependency risks, deviations from your standards and best practices, and expansion of access controls in CloudFormation that go beyond best practices. It also builds and runs your code in an AWS-managed sandbox to better assess any production risks.
  • Perform exploratory release testing for deployed applications — If you deploy your web or API application to a production-like environment, Kiro can have the DevOps Agent run an exploratory tests on it. Any bugs or regressions found can be fixed without leaving the IDE.

How it works

The power provides two complementary workflows that Kiro selects automatically based on your request:

  • Chat (updates in seconds) — For instant answers about cost, architecture, topology, and knowledge discovery. Kiro creates a conversation with the DevOps Agent and streams responses in real time. Follow-up questions retain full context within the same session.
  • Investigation (completes in minutes) — For complex incidents requiring deep analysis. The DevOps Agent examines CloudWatch metrics, X-Ray traces, deployment history, and service topology, then delivers a root cause analysis with prioritized recommendations.

The following diagram shows how Kiro combines local workspace context with the DevOps Agent’s cloud intelligence:

Kiro combines local workspace context with the DevOps Agent's cloud intelligence through the AWS DevOps Agent MCP Server.

Figure 1: Kiro combines local workspace context with the DevOps Agent’s cloud intelligence through the AWS DevOps Agent MCP Server.

Prerequisites

Before using the power, ensure you have:

  1. AWS credentials configured (AWS IAM Identity Center recommended) if using AWS SigV4.
  2. Kiro installed and a workspace set up
  3. An AWS DevOps Agent agent space configured with data sources (CloudWatch, X-Ray, or other integrations)
  4. Create an access token or have AWS SigV4 configured. The access tokens feature must be enabled on your Agent Space for access tokens to work.
  5. For access tokens, you must have IAM permissions to manage access tokens (aidevops:CreateAccessToken, aidevops:RevokeAccessToken, aidevops:RotateAccessToken).
    • Enable access tokens
      • Review the security best practices detailed in the connect to DevOps Agent Remote Server documentation.
      • Sign in to the AWS Management Console and open the AWS DevOps Agent console.
      • Choose your Agent Space.
      • Choose the Configuration tab.
      • In the Access tokens section, choose Enable.
      • Confirm the action.
    • Create a token
      • Open the DevOps Agent web app for your Agent Space, then from the navigation menu, choose Settings, then choose Access Tokens.
      • Choose Create access token.
      • Enter a name for the token.
      • Choose a scope:
      • read – View investigations, recommendations, chats, and Agent Space resources.
      • operate – Full access. Includes everything in read, plus send messages, create chats, and manage backlog tasks and recommendations.
      • Set an expiration (1 to 60 days).
      • Copy the token value and store it in a safe, secure location. You cannot retrieve it again.
      • After creating a token, the web app displays a configuration example that you can copy directly into your client.

The power works with any agent space that has active data sources. The more data sources connected, the richer the investigations and recommendations.

Getting started with the Kiro power for AWS DevOps Agent

Setting up the power takes only a few steps. You can install it directly or follow these steps:

  1. Open Kiro and choose the Powers icon in the sidebar.
  2. In the AVAILABLE panel, find AWS DevOps Agent.
  3. Choose Install.
  4. The power appears in the INSTALLED panel, and choose Try power.
Kiro powers panel showing the Kiro power for AWS DevOps Agent

Figure 2: Kiro powers panel showing the Kiro power for AWS DevOps Agent

Verify Installation

After installation, you should see the Kiro power for AWS DevOps Agent listed in the powers section of the Kiro panel. Navigate to mcp.json file and change these values accordingly, and save the config file.

  • DEVOPS_AGENT_TOKEN=<your-token>
  • DEVOPS_AGENT_REGION=<your-agent-space-region>

In the MCP Servers panel, you will see DevOps Agent MCP connected and also displays list of tools. The power activates automatically when you mention relevant keywords like incident, cost optimization, architecture review, or topology in your conversation.

Figure 3: MCP Servers panel showing the AWS DevOps Agent MCP and connected tools

Figure 3: MCP Servers panel showing the AWS DevOps Agent MCP and connected tools

Walkthrough: Investigating a production incident

Let’s walk through a realistic scenario. Your team receives a CloudWatch alarm: an Amazon ECS service is returning HTTP 503 errors and task restarts have spiked.

Step 1: Describe the problem

In Kiro, you type:

“My ECS service checkout-api is throwing 503 errors. The alarm fired 10 minutes ago. Here’s the error from my logs: Connection pool exhausted, max connections 50 reached.”

Because Kiro has access to your workspace, it automatically includes relevant context — your task definition, your connection pool configuration from application.yml, and your recent git commits.

Step 2: Kiro starts the investigation

Kiro routes this to the investigation workflow. You see real-time progress as findings stream in:

  • Planning investigation approach…
  • Querying CloudWatch metrics, ECS task events, X-Ray traces…
  • Analyzing connection pool metrics against task count…
  • Root cause identified: Connection pool sized for single task, but service scaled to 5 tasks sharing a database connection limit

Step 3: Review findings and recommendations

The DevOps Agent returns a detailed analysis:

Root cause: The database connection limit (50) is shared across all ECS tasks. When the auto-scaling policy added tasks at 08:47 UTC, each task attempted to open 50 connections, exceeding the Amazon RDS max_connections parameter (100).

Recommendation and Mitigation: Reduce the per-task connection pool to max_connections / max_tasks (100 / 5 = 20 per task), or increase the RDS instance class to support more connections.

Step 4: Generate and apply the fix

You ask Kiro to implement the recommendation. Because it has access to your application.yml and your AWS CloudFormation template, it generates a targeted fix:

  • Updates spring.datasource.service.maximum-pool-size from 50 to 20 in your application configuration
  • Adds a comment explaining the calculation
  • Suggests an RDS parameter group change if you want to increase capacity instead

The fix is applied directly in your workspace, ready for review and commit.

Operating across multiple agent spaces

If your team manages multiple applications, each with its own DevOps Agent agent space, you can switch between them naturally. Kiro lists available agent spaces and routes your question to the right one.

Conclusion

The Kiro power for AWS DevOps Agent brings the full operational intelligence of AWS DevOps Agent into the IDE where you already work. By combining your local workspace context with cloud-side analysis, it closes the loop from detection to remediation without context switching.

Whether you are triaging a production incident, optimizing costs across services, or onboarding a new team member who needs to understand your infrastructure, the power provides contextual answers grounded in your actual AWS environment.

Install the Kiro power for AWS DevOps Agent today and experience AI-powered cloud operations in your IDE. To learn more, visit the Interfacing with AWS DevOps Agent and the Kiro powers documentation.

Tipu Qureshi Tipu Qureshi
Tipu Qureshi is a Senior Principal Technologist in AWS Agentic AI, focusing on operational excellence and incident response automation. He works with AWS customers to design resilient, observable cloud applications and autonomous operational systems.
Shashiraj Jeripotula (Raj) Shashiraj Jeripotula (Raj)
Shashiraj Jeripotula (Raj) is a San Francisco-based Principal Partner Solutions Architect at AWS. He works with ISV and AWS partners to build deep integrations across observability, AI, and agentic development tooling — helping developers leverage AI agents, Model Context Protocol (MCP), and shift-left observability to build responsible, production-ready AI systems on AWS.