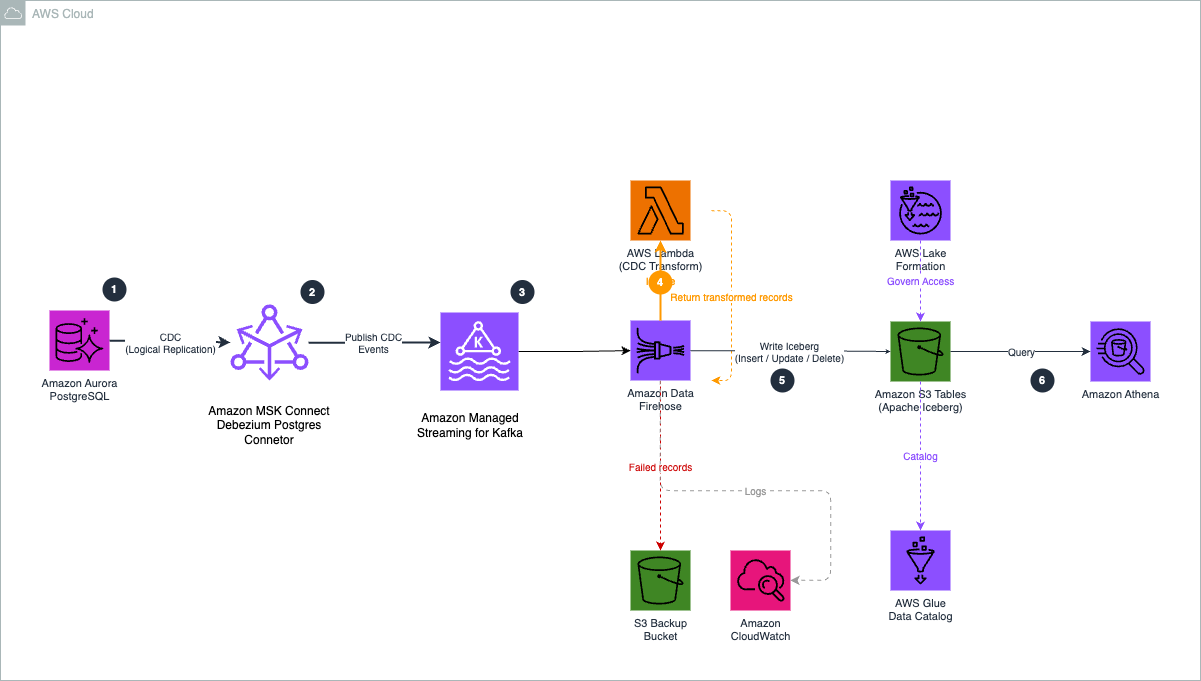
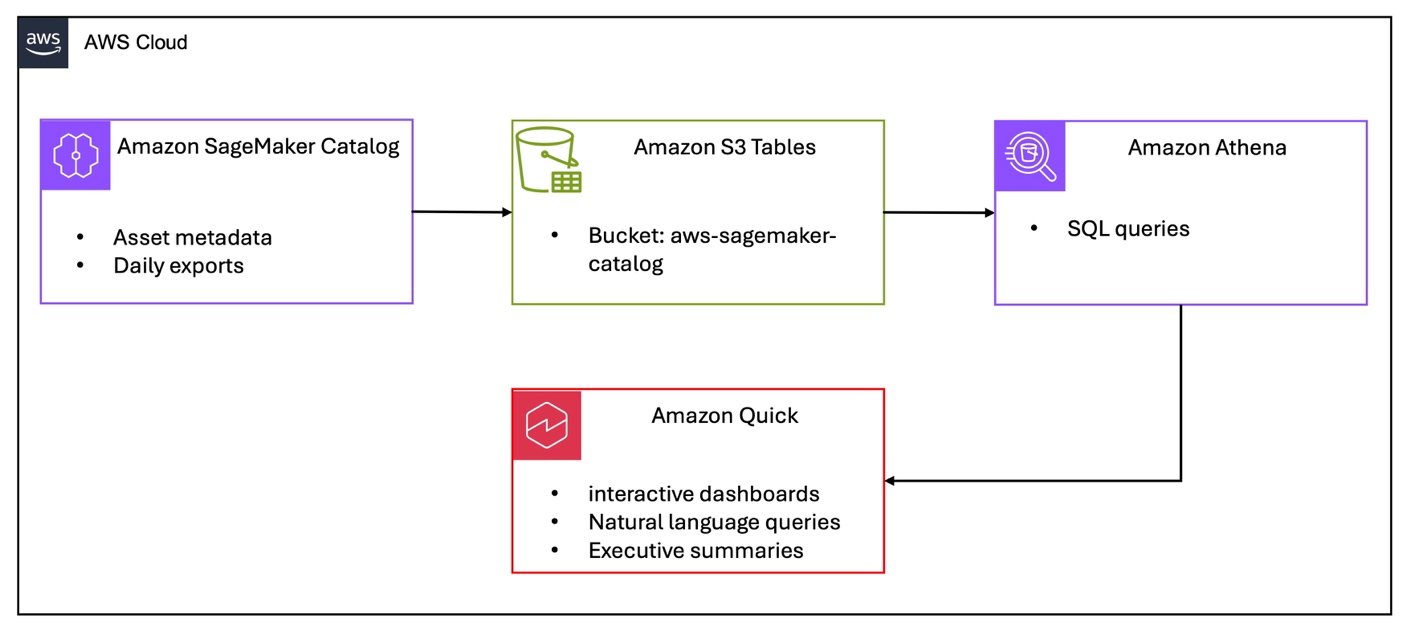
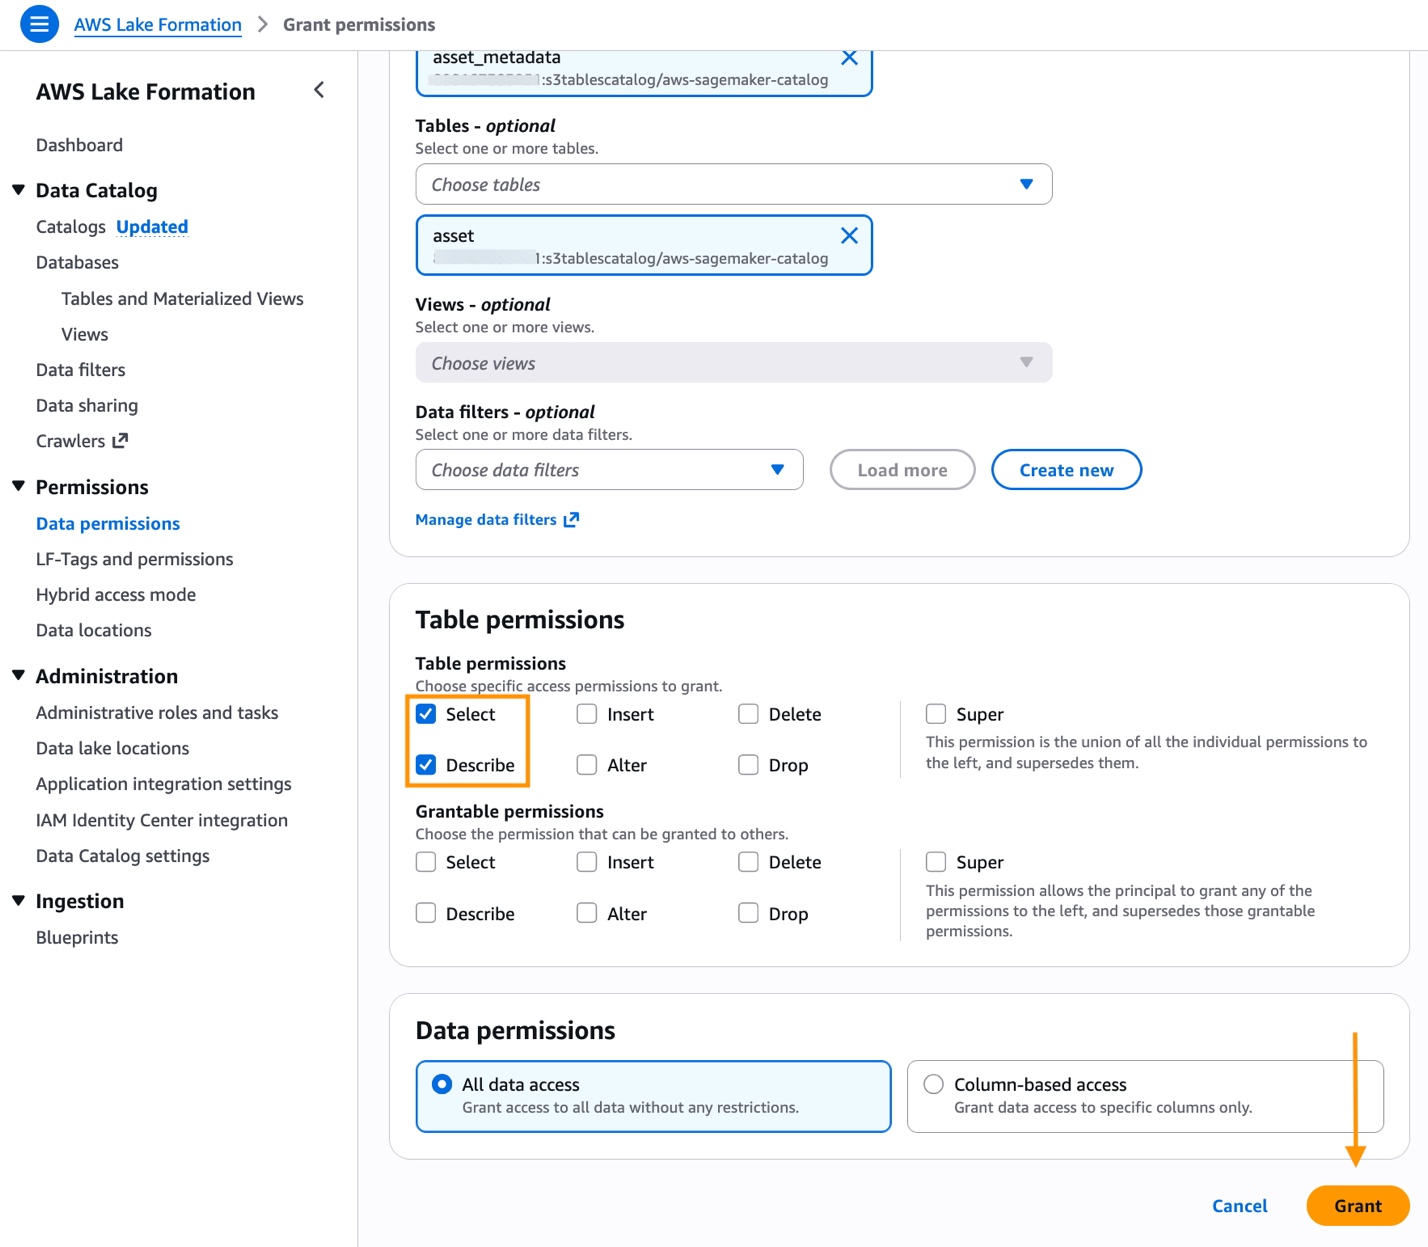
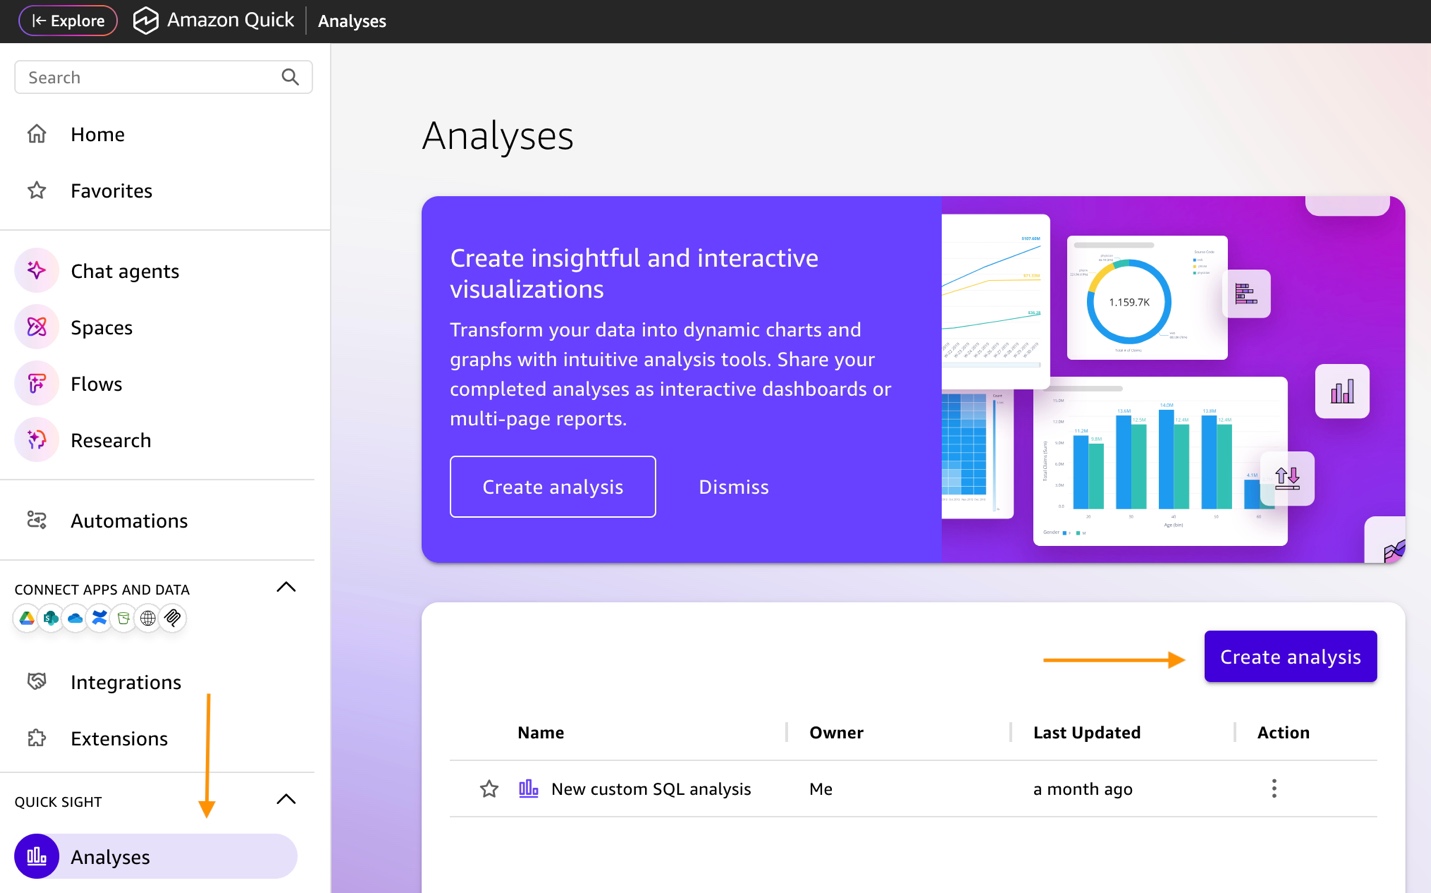
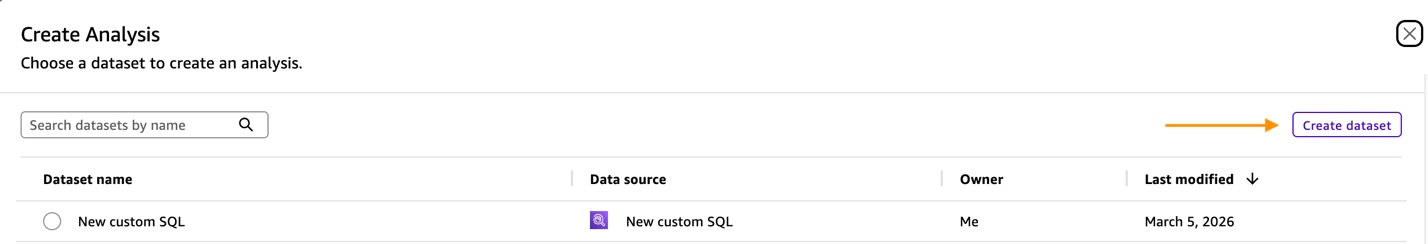
With Private Networking for Amazon MQ for RabbitMQ, your brokers can establish outbound connections to private resources in your VPC without exposing those resources publicly. This post explains how the feature works and walks you through setting it up.
Amazon MQ for RabbitMQ brokers could previously only reach external destinations over the public internet. If you used a private Lightweight Directory Access Protocol (LDAP) server for broker authentication, you had to expose that server publicly. If you wanted to federate messages between private brokers, you needed workarounds like Network Load Balancers with IP allowlisting, as described in Implementing Federation on Amazon MQ for RabbitMQ Private Brokers. Private Networking removes those constraints.
You can connect your broker to private identity providers, other Amazon MQ for RabbitMQ brokers, or self-hosted RabbitMQ brokers running in private subnets. Combined with cross-Region networking services like AWS Transit Gateway, you can extend these connections across AWS Regions and accounts, with traffic staying on the AWS private network.
You create a VPC Lattice resource gateway in a VPC that can reach your private destination. You then create a VPC Lattice resource configuration that defines the destination, such as an IP address or Domain Name System (DNS) name. You add the resource configuration to a RAM resource share and associate the resource share with your broker through the UpdateBroker API operation. After rebooting the broker, the network path is active and your broker can reach the private destination.
The broker does not need to be private. A publicly accessible broker works the same way.
What you can connect to
Private Networking supports three use cases.
Private identity providers
If you use an LDAP server or other identity provider for RabbitMQ authentication, you no longer need to expose it publicly. Create a resource configuration pointing to your identity provider, associate it with your broker, and use the DNS name returned by the DescribeSharedResources API operation in place of the public endpoint. Follow the existing guidance for setting up an identity provider, substituting the private DNS name.
Self-hosted RabbitMQ brokers
You can use Shovel or Federation to connect your Amazon MQ for RabbitMQ broker to a self-hosted RabbitMQ broker running in a private subnet. Create a resource configuration pointing to the self-hosted broker and use the DNS name from the DescribeSharedResources API operation in your Shovel or Federation configuration.
You can federate or shovel messages between two Amazon MQ for RabbitMQ brokers using Private Networking. Create a resource configuration pointing to the destination broker’s endpoint and specify that same endpoint as the custom domain name on the resource configuration. This helps to verify that the DNS name resolves correctly and Transport Layer Security (TLS) peer verification succeeds.
This extends to brokers in different AWS Regions and different AWS accounts. By combining Private Networking with cross-Region networking services like AWS Transit Gateway or VPC peering, you can build a fully private federation or shovel path between brokers, with no public endpoints required.
DNS names and custom domains
Each resource configuration can include a custom domain name. If you add a verified domain, that domain resolves to the private destination. If you do not add a verified domain, Amazon MQ provides a DNS name for the broker’s private connection. Retrieve this DNS name with the DescribeSharedResources API operation.
If you specify an unverified domain on a resource configuration, it is ignored. The broker’s private connection receives a private DNS name instead, which you can retrieve with the DescribeSharedResources API operation.
Note: If you are running RabbitMQ 4, review this section before configuring Shovel or Federation connections.
RabbitMQ 4 enforces TLS certificate peer verification by default for Shovel and Federation connections. RabbitMQ 3 does not enforce this by default. When using Private Networking, the DNS name that Amazon MQ assigns to the private connection will not match the TLS certificate of the destination, which causes peer verification to fail.
The recommended approach is to specify the destination broker’s endpoint (for example, b-a1b2c3d4-5678-90ab-cdef-EXAMPLE11111.mq.us-east-1.on.aws) as the custom domain name on the resource configuration. This exception only applies to Amazon MQ for RabbitMQ broker endpoints. You cannot use an unverified domain for self-hosted brokers. Specifying the Amazon MQ endpoint causes the DNS name to match the destination’s TLS certificate, and peer verification succeeds. This approach works regardless of your RabbitMQ version and avoids the issue entirely.
Getting started
To get started with Private Networking for Amazon MQ for RabbitMQ, follow these steps.
Create a VPC Lattice resource gateway in a VPC that can reach your private destination. Make sure the resource gateway’s security group allows outbound traffic to your destination on the required port (for example, port 5671 for AMQPS (AMQP over TLS) or port 636 for LDAPS (LDAP over TLS)). The resource gateway must share at least one Availability Zone with the broker. Cluster brokers cover multiple Availability Zones, so this is satisfied. For single-instance brokers, verify the Availability Zone overlap.
Create a VPC Lattice resource configuration pointing to your private destination (IP address or DNS name). If you’re connecting to another Amazon MQ broker, specify the destination broker’s endpoint as the custom domain name on the resource configuration, as shown in the following figure.Figure 1: VPC Lattice resource configuration showing the custom domain name field and resource definition populated with the Amazon MQ broker endpoint.
Add the resource configuration to a RAM resource share. The resource share must allow external principals, as shown in the following figure.Figure 2: RAM resource share configuration with the Allow external principals option selected.
Associate the resource share with your broker by editing the broker and adding the resource share. You can also do this using the update-broker command with the AWS CLI. You must pass the entire list of resource share ARNs you want on the broker. This is a put operation, not an add or remove operation.
The associated RAM resource share appears as shown in the following figure.
Figure 3: Network settings view with associated RAM resource shares.
Select the resource share in the Associated RAM resource shares section. The network status of each shared resource is displayed in the Shared resources section, as shown in the following figure.
Figure 4: RAM resource share selection showing the network status of each shared resource.
Reboot the broker from the AWS Management Console or the AWS CLI to create the network path:
Use the DNS name returned in the output in your Shovel, Federation, or identity provider configuration. Adding new resource configurations to an existing RAM resource share does not automatically update the broker. You must call update-broker and reboot the broker for the new resource configurations to take effect.
Cleaning up
Private Networking uses VPC Lattice and PrivateLink resources that incur ongoing charges. If you no longer need the private connection:
Call update-broker with the resource share removed from the list (or an empty list to remove all), then reboot the broker.
After the broker reboot completes and the resources are no longer in use, delete the VPC Lattice resource configuration and resource gateway.
Optionally, remove the Amazon MQ account principal from the RAM resource share. This principal may still be in use if other brokers are associated with the same resource share, so only remove it if no other brokers depend on it.
If you created a new Amazon MQ for RabbitMQ broker for this walkthrough and no longer need it, delete the broker from the Amazon MQ console or with the delete-broker command.
Operational behavior: Resource access and reboots
Removing a VPC Lattice resource configuration from a RAM resource share while the broker is actively using it revokes access immediately, with no reboot required. Removing a principal from a RAM resource share has the same effect: brokers associated through that principal lose access to the resources in the share immediately. These are intentional security behaviors managed by RAM and VPC Lattice.
Adding new resource configurations to an existing resource share does not take effect automatically. You must call update-broker and reboot the broker for the new resource configurations to take effect. This is by design. It helps verify that changes to a resource share only reach the broker when someone with broker management permissions explicitly triggers the update, providing clear security separation between share management and broker management.
Private Networking is available for Amazon MQ for RabbitMQ brokers in all the AWS Regions where Amazon VPC Lattice is available. Amazon MQ for ActiveMQ brokers do not support this feature.
Pricing
Private Networking uses Amazon VPC Lattice and AWS PrivateLink. Data processing and data transfer charges apply to traffic sent through the private connection. There is an Amazon MQ pricing of $0.01 per GB of data processed through the resource endpoint. For details, see the Amazon MQ pricing page, VPC Lattice pricing page and AWS PrivateLink pricing page.
Conclusion
In this post, we explained how Private Networking for Amazon MQ for RabbitMQ works and walked through the setup process. Whether you’re securing a private identity provider, federating messages between brokers, or connecting to self-hosted RabbitMQ, your broker can now reach private destinations without exposing them publicly.
When downsizing an Amazon Elastic Compute Cloud (Amazon EC2) instance, teams often evaluate CPU and memory utilization but overlook the instance’s Amazon Elastic Block Store (Amazon EBS) performance limits for throughput and IOPS. Smaller Amazon EBS-optimized instance types have lower baselines and rely on burst credits to handle peaks. If your workload’s I/O pattern drains those credits faster than the instance can refill them, the instance will throttle your workload to baseline. This post applies to burstable EBS-optimized instances with baselines below their maximum.
This post shows how to pull your instance’s Amazon EBS metrics from Amazon CloudWatch, simulate the burst credit balance against a target instance type’s limits, and help evaluate whether the downsize might be appropriate before making the change.
Solution overview
The analysis compares your workload’s actual I/O pattern against the target instance type’s Amazon EBS limits.
Measure your current Amazon EBS usage. Pull instance-level throughput and IOPS from Amazon CloudWatch at 5-minute granularity. You need at least two weeks of data to capture weekly patterns. Four weeks is better if your workload has monthly cycles. While you pull data, check whether your current instance already hits its Amazon EBS-optimized performance limits.
Compare against the target instance’s limits. Look up the baseline and burst ceiling for your target instance type. Simulate the burst credit balance across your observation window: for each 5-minute interval, calculate whether credits are draining or refilling, and track whether the balance ever hits zero. If it does, you will experience throttling on the smaller instance.
Monitor after the move. Watch InstanceEBSThroughputExceededCheck and InstanceEBSIOPSExceededCheck for immediate throttle detection. Track EBSByteBalance% and EBSIOBalance% to gauge how much headroom remains for workload growth.
Note: These balance metrics are only available on burstable instance sizes where the baseline is lower than the maximum.
Prerequisites
An AWS account with permissions for cloudwatch:GetMetricData and ec2:DescribeInstanceTypes. The instance must be Amazon EBS-optimized (AWS enables EBS-optimization by default on most current-generation instance types).
Note: AWS doesn’t provide these instance-level Amazon CloudWatch metrics in AWS Outposts, AWS Local Zones, or AWS Wavelength Zones.
Pulling instance-level Amazon EBS metrics from Amazon CloudWatch
Amazon CloudWatch provides Amazon EBS metrics at the instance level in the AWS/EC2 namespace, using the InstanceId dimension. Here are the metrics that you need:
Metric
What it measures
EBSReadBytes
Total read bytes in the period
EBSWriteBytes
Total write bytes in the period
EBSReadOps
Total read operations in the period
EBSWriteOps
Total write operations in the period
EBSIOBalance%
IOPS burst credit balance (0-100%)
EBSByteBalance%
Throughput burst credit balance (0-100%)
InstanceEBSIOPSExceededCheck
1 if instance hit IOPS limit, 0 otherwise
InstanceEBSThroughputExceededCheck
1 if instance hit throughput limit, 0 otherwise
The first four metrics are the inputs for the simulation. The rest are useful context:
EBSIOBalance% and EBSByteBalance% show how much of the burst credit pool remains, as a percentage. On the current (larger) instance, these should sit at or near 100 percent. If they’re dipping, the workload is already consuming burst credits at the current size, and a downsize will make it worse.
Note: These metrics only appear on instances where the baseline is lower than the maximum.
InstanceEBSIOPSExceededCheck and InstanceEBSThroughputExceededCheck are binary: 1 means the instance hit its EBS-optimized performance limit within the last minute. If either is firing on the current instance, the workload is already throttling and should be addressed before considering a downsize.
Pull these at 5-minute granularity for at least two weeks (four if your workload has monthly cycles). Amazon CloudWatch retains 5-minute data points for 63 days, so that’s your upper bound. You can retrieve the data through the AWS Command Line Interface (AWS CLI) (GetMetricData API), the Amazon CloudWatch console, or any AWS SDK. The metrics live in the AWS/EC2 namespace with your InstanceId as the dimension.
Use the Maximum statistic for the four I/O metrics and Minimum for the balance percentages. Maximum captures the highest 1-minute data point within each 5-minute window, which is the conservative choice for the simulation inputs. The Sum statistic gives a more precise total for each interval, but Maximum is the intentionally conservative choice. It assumes the peak 1-minute rate held for the full 5-minute window, which overstates actual consumption. Minimum on the balance metrics captures the lowest point the balance hit within each window, so you see the actual dips rather than averaging them away. For the ExceededCheck metrics, use Maximum (you want to know if the limit was hit at any point in the window).
Combine read and write values to get totals per interval. To convert to per-second rates:
The division by 60 (not by the period length) is intentional. The Maximum statistic for a 5-minute period returns the highest 1-minute aggregate within that window, not a 5-minute total. Dividing by 60 converts that 1-minute peak to a per-second rate. The additional divisions by 1,024 convert bytes to mebibytes to match the units in describe-instance-types.
Comparing actual usage against target limits
From the Amazon EBS-optimized instances documentation, find the baseline and maximum (burst ceiling) for both IOPS and throughput on your target instance type. You can also pull these programmatically:
This returns the baseline and maximum bandwidth (MB/s) and IOPS for the instance type. Note that BandwidthInMbps is megabits per second (network-style units), while ThroughputInMBps is megabytes per second. The throughput values are what you compare against your Amazon CloudWatch data.
BaselineThroughputInMBps is the sustained rate the instance can deliver indefinitely. MaximumThroughputInMBps is the burst ceiling, the absolute maximum the instance can deliver while it has burst credits. Same relationship for IOPS. IOPS and throughput have separate burst budgets, tracked by EBSIOBalance% and EBSByteBalance% respectively.
How burst credits work
The instance maintains a credit pool for each budget (IOPS and throughput). The pool capacity is:
credit_pool = (burst_ceiling - baseline) * 1800
The 1800 comes from 30 minutes (1800 seconds) of burst at the maximum rate, which AWS provisions as the pool size for burstable Amazon EBS-optimized instances. Credits drain when usage exceeds baseline and refill when usage is below baseline, at a rate of baseline – effective_usage per second, where effective_usage is min(actual_usage, burst_ceiling). The instance cannot deliver more than the ceiling regardless of credit balance, so credits drain at the ceiling rate, not the requested rate. The pool is capped at its maximum and floored at zero. When credits hit zero, your workload is throttled to baseline performance. AWS resets the pool to full every 24 hours, giving you at least 30 minutes of burst capacity per day.
With the time series data and the target limits, you can simulate what the credit balance would look like on the smaller instance. For each 5-minute interval in your observation window:
Where interval_seconds is 300 for 5-minute data or 60 for 1-minute data.
When actual usage is below baseline, credits accumulate. When above, they drain. Run this across the full observation window, resetting the pool to full at the start of each 24-hour period to model the AWS top-off guarantee. Start each day with a full pool, then drain and refill through the day’s intervals. If the balance hits zero on any day, the workload will throttle on the smaller instance.
Run the simulation twice: once for IOPS, once for throughput. Throttling happens if either pool hits zero.
A Python script that pulls Amazon CloudWatch data for a given instance ID, looks up the target instance type’s Amazon EBS limits, and runs this simulation end-to-end is available at sample-ec2-ebs-burst-analyzer repository.
This simulation is an approximation
It models credit behavior at 5-minute (or 1-minute) granularity using Amazon CloudWatch aggregates, not the actual per-second I/O stream. Two factors make the simulation more conservative than reality, and two can make reality worse than the simulation.
The Maximum statistic returns the highest 1-minute total within each 5-minute window. The simulation applies that peak rate across the full 300-second interval. This overestimates credit drain by up to 5x for any given interval, because the other 4 minutes likely had lower usage. The tradeoff is intentional. If the simulation says the workload fits, the result is reliable. If it says the workload doesn’t fit, the actual situation might be better than predicted. In that case, re-run with the Average statistic for a less conservative check, or pull 1-minute data (available for the most recent 15 days in Amazon CloudWatch) for higher fidelity.
Working in the other direction, two things can make the real situation worse than the simulation predicts. If the downsize also reduces memory, database workloads (SQL Server buffer pool, PostgreSQL shared_buffers, Oracle SGA) will generate more disk I/O than what you measured because the smaller cache forces more page reads from Amazon EBS. Account for this by including additional headroom in the burst credit budget. And I/O spikes that last milliseconds don’t show up in 5-minute Amazon CloudWatch data. If EBSByteBalance% or EBSIOBalance% are trending down on the current instance but your throughput metrics look fine, the workload is microbursting.
What to look for in the results
The simulation produces two outputs per budget (IOPS and throughput): the low-water mark (lowest credit balance across the observation window) and the number of intervals where the balance hit zero.
IOPS credit balance (EBSIOBalance%) – If the simulated low-water mark stays well above zero, the workload’s IOPS pattern fits within the target’s burst budget. A low-water mark of 90 percent means the workload barely touches the IOPS burst pool. A low-water mark of 40 percent means it fits today but has limited room for IOPS growth.
Throughput credit balance (EBSByteBalance%) – Same logic for throughput. Check this independently because a workload can be comfortable on IOPS but tight on throughput, or the reverse.
Intervals at zero – If either balance hits zero on any day, the workload will throttle to baseline on this instance type.
Peak usage vs. burst ceiling – The ceiling is the absolute maximum regardless of credit balance. If your peak throughput exceeds MaximumThroughputInMBps or peak IOPS exceeds MaximumIops, the instance will cap I/O at the ceiling rate during those intervals. This doesn’t mean the workload doesn’t fit overall (credits might still be fine), but the application will experience reduced I/O during those peaks. A handful of brief spikes may be acceptable. Sustained ceiling breaches are a stronger signal to size up.
Throttled intervals – The most direct measure of impact. A throttled interval is one where the credit balance is at zero and usage exceeds baseline. During these intervals, the instance cannot deliver what the workload is asking for. A few throttled intervals during a nightly batch may be tolerable. Dozens per day during business hours is a problem.
The following two figures show what these outcomes look like. In the first, the workload bursts above baseline during business hours but credits never fully deplete. The minimum balance stays at 82 percent, well above zero. This workload is safe to downsize.
In the second figure, the same workload runs on a smaller instance type with a lower burst pool. Credits deplete within the first burst window and stay near zero for most of the business day. This workload would throttle on the smaller instance.
The following servers are from a customer running SQL Server on EC2. We simulated the burst credit balance for each against the proposed target instance type, using 28 days of Amazon CloudWatch data at 5-minute granularity with the Maximum statistic.
Server A: fits comfortably (current: c6in.4xlarge; proposed: r6i.large)
Simulating the credit balance across 28 days with a daily pool reset:
IOPS
Throughput
Credit pool
65,520,000
2,103,750 MB
Low-water mark
52,084,325 (79.5%)
1,656,415 MB (78.7%)
Intervals at zero
0
0
On the worst day for throughput, here’s what the simulation looks like during the evening burst window, showing how credits drain and recover interval by interval:
Time
Throughput (MB/s)
Net credit change
Balance
Balance %
22:00
154.25
-21,900
1,854,076
88.1%
22:05
22.57
+17,603
1,871,679
89.0%
22:10
452.16
-111,273
1,760,406
83.7%
22:15
427.89
-103,991
1,656,415
78.7%
22:20
30.99
+15,077
1,671,492
79.5%
At 22:10 and 22:15, throughput spiked above 400 MB/s, well above the 81.25 MB/s baseline but still under the 1,250 MB/s burst ceiling. Each interval drained roughly 100,000 credits. The pool hit its low-water mark of 78.7 percent at 22:15, then immediately began recovering as throughput dropped. By 23:55, the pool was back to 100 percent.
Assessment: fits, with roughly 20 percent headroom on the worst day.
Server B: fits but tight (same workload as Server A; proposed: r5.large)
Same workload, same burst pattern, but the r5.large has a smaller credit pool, so the same spikes drain a larger percentage. The throughput low-water mark drops from 78.7 percent to 51.5 percent. The same evening burst window that used 20 percent of the r6i.large pool now consumes nearly half the r5.large pool:
Time
Throughput (MB/s)
Net credit change
Balance
Balance %
22:00
154.25
-21,900
672,826
72.9%
22:05
22.57
+17,603
690,429
74.8%
22:10
452.16
-111,273
579,156
62.8%
22:15
427.89
-103,991
475,165
51.5%
22:20
30.99
+15,077
490,242
53.1%
This still fits, but with limited margin. Any workload growth (more users, larger databases, additional backup jobs) could push the balance toward zero. Separately, a single IOPS interval reached 20,226, exceeding the r5.large burst ceiling of 18,750. The instance can only deliver up to the ceiling while credits remain, so the application received 18,750 IOPS during that interval. That single spike would not cause sustained throttling, but combined with the tight throughput margins, it confirms this workload is at the boundary of what r5.large can handle.
Assessment: fits today, but not a safe long-term choice.
Server C: ceiling breach (current: c6in.4xlarge; proposed: r6i.xlarge)
Peak throughput: 1,502.94 MB/s. This exceeds the 1,250 MB/s burst ceiling. During those peak intervals, the instance would cap throughput at 1,250 MB/s while credits remain. If credits are exhausted, throughput drops to the 156.25 MB/s baseline. The credit simulation might still show the workload fits (credits never hit zero), but the application would experience reduced I/O during those peaks. For this customer, the peaks coincided with production SQL Server activity, so even brief throttling wasn’t acceptable, and a larger instance type was needed.
Assessment: workload will be throttled during peak intervals. Whether that’s acceptable depends on the application’s sensitivity to I/O latency.
Monitoring after the resize
The pre-migration analysis uses historical data from the larger instance. After you resize, real metrics replace the simulation. Monitor the following three layers:
InstanceEBSThroughputExceededCheck and InstanceEBSIOPSExceededCheck = 1 means the instance is actively throttling. This is the definitive signal. Alarm on Sum > 0 over 3 consecutive 1-minute periods to filter out single-second spikes that resolve on their own.
EBSByteBalance% and EBSIOBalance% trending downward over days or weeks means the workload is growing into the instance’s limits. You’re not throttling yet, but you’re on a trajectory. An instance that dips to 90 percent nightly and recovers is in a different position than one that dips to 40 percent and barely recovers before the next burst. Neither instance is throttling, but the first has headroom while the second doesn’t.
EBSByteBalance% and EBSIOBalance% stay at 100 percent means the workload never exceeds baseline. The instance has unused capacity, and you might even be able to go smaller.
If the workload has weekly patterns, allow at least one full week of data before drawing conclusions.
Conclusion
In this post, we showed how to simulate the EBS-optimized instance burst credit balance against a target instance type’s limits before downsizing an Amazon EC2 instance. The approach pulls Amazon CloudWatch metrics at 5-minute granularity, compares actual throughput and IOPS against the target’s baseline and burst ceiling, and tracks whether the credit balance would hit zero during the observation window.
This covers the Amazon EBS dimension of a right-sizing decision. A complete evaluation also considers CPU utilization, memory usage, and network throughput against the target instance’s limits. For workloads where Amazon EBS utilization is well below baseline, the burst credit simulation might not be necessary.
In this blog post you’ll learn how to detect and prevent subdomain takeover – a tactic where threat actors exploit dangling DNS records to redirect traffic to attacker-controlled resources. We’ll explain the issue, how the situation arises, and how you can use various AWS features and services to help mitigate the impact of this tactic.
Under the shared responsibility model, securing configurations in the cloud is your responsibility. AWS supports you through strong defaults, guidance in the Security Pillar of the Well-Architected Framework, and security services to help you meet that responsibility. The AWS Customer Incident Response Team (AWS CIRT) also monitors for new and trending tactics that threat actors use to exploit specific customer configurations, so that you can make informed design decisions and improve your response plans.
AWS CIRT has observed threat actors actively scanning for public DNS CNAME records that point to resources that no longer exist, looking for subdomain takeover opportunities.
Note: The subdomain takeover tactic does not leverage vulnerabilities of AWS services. It exploits a dangling DNS record to redirect traffic to an attacker-controlled resource.
Quick DNS Primer
CNAME Records: A CNAME (Canonical Name) record is a DNS entry that points one domain name to another. For example, api.example.com can be configured to point to api.example.s3-website-us-east-1.amazonaws.com. This feature of DNS enables users to configure a memorable, human-friendly domain name while the actual resource lives at a longer, machine-generated AWS hostname. A security issue emerges when the target resource is deleted but the CNAME record pointing to it remains – creating a “dangling” record.
Dangling Records: When a resource (like an S3 bucket) is deleted but the DNS record pointing to it is left behind, that DNS record becomes “dangling”, pointing to a resource that no longer exists. For resources in globally shared namespaces, threat actors can potentially reclaim the name of your deleted resource and serve malicious content through your DNS record.
What is subdomain takeover?
A subdomain is a prefix added to a domain that allows you to organize access to your resources. A subdomain takeover occurs when you delete the underlying resource and a threat actor creates a new resource with the same name to take advantage of the DNS records still pointing to it.
A subdomain takeover is possible when a CNAME record points to an AWS resource that uses a globally shared DNS namespace where the resource name can be chosen by any AWS customer. The following AWS resources meet these criteria:
Amazon S3 (global namespace): Bucket names like mybucket.s3.amazonaws.com are globally unique and can be claimed by any account if the bucket is deleted. Note: S3 buckets created with account regional namespaces (launched March 2026) are scoped to your account and are not subject to this issue.
Amazon CloudFront: Distribution domain names like d111111abcdef8.cloudfront.net are assigned by AWS and cannot be chosen by an attacker. However, if you delete a distribution and another customer creates one that happens to receive the same domain name, a dangling CNAME could resolve to their content.
AWS Elastic Beanstalk: Environment names like myapp.elasticbeanstalk.com are globally unique and can be claimed by any account if the environment is terminated.
Resources like Amazon VPC, Amazon EC2 instances, or private hosted zones are not subject to this tactic because they do not expose globally claimable DNS namespaces.
You create a DNS CNAME record pointing to your S3 website endpoint. The subdomain subdomain.example.com now resolves to subdomain.example.s3-website-us-east-1.amazonaws.com, which serves content from the S3 bucket named subdomain.example. If your team deletes the bucket and forgets to delete the DNS record, users that navigate to the site will see an error stating that the bucket doesn’t exist. However, at this point, if a threat actor sees this error and moves in to claim the bucket name, they will be able to set up their own site that users will see when they navigate to the subdomain.example.com site.
Figure 1 shows an S3 bucket named subdomain.example (a globally unique bucket name) configured to host a static website, with the S3 website endpoint subdomain.example.s3-website-us-east-1.amazonaws.com.
Figure 1: S3 bucket configured as a static website
As shown in Figure 2, we use Amazon Route 53 to create a CNAME record to resolve to our Amazon domain name; to give users a friendly name and so they do not have to remember the long S3 website name in URLs.
Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket
The customer’s AWS administrator decides to stop serving content from the S3 bucket and deletes it, as shown in Figure 3.
Figure 3: Resource deleted without removing the CNAME record
With the S3 bucket deleted and the CNAME record still in place, the DNS record is now dangling. A threat actor identifies this situation and creates a new S3 bucket with the same global name subdomain.example in an AWS account that the threat actor controls, as shown in Figure 4. The threat actor can now serve content from this new bucket, including potentially malicious content. End users remain unaware of this switch and continue to access subdomain.example.com, trusting the content because it appears to originate from a URL they recognize.
Figure 4: Subdomain takeover happens
Potential impacts of a sub-domain takeover
Consider these potential impacts:
Reputation risk: There is a potential risk to your organization’s reputation, because you don’t control the content being served from the threat actor’s site that your DNS record points to.
Potential exposure to phishing campaigns: Users within your organization might have the subdomain bookmarked in their browser, not knowing the resource is no longer available, then unsuspectingly navigate to the site that now hosts malware or is used to phish user credentials.
Blocking: If the subdomain is flagged by security vendors for malicious activity, it could impact your business operations.
Financial loss: Subdomain takeover incidents can result in a financial impact due to the potential disruption to service delivery as you deal with the event.
Proactive detection
AWS Config for proactive detection
For proactive detection, you can use AWS Config to continuously monitor your Route 53 CNAME records and verify that the target resources exist in your account.
Prerequisite: This approach requires AWS Config recorder to be enabled for the resource types you want to monitor (S3 buckets, CloudFront distributions, Elastic Beanstalk environments). If Config isn’t recording a resource type, it won’t appear in the inventory check. For more information, see Setting up AWS Config with the console.
Why use AWS Config inventory instead of DNS resolution checks?
A common approach is to check whether a CNAME resolves to a valid endpoint. However, this method has a critical flaw: if an attacker has already claimed the resource, DNS resolution will succeed – to their resource, not yours. You would have no indication that you don’t own what’s responding.
By querying AWS Config’s recorded configuration items, you’re checking whether the resource exists in your account inventory, not just whether something responds at that DNS name. This approach correctly identifies dangling CNAMEs even after a takeover has occurred.
Implementation approach:
Account-level vs. organization-level scope
The reference implementation queries AWS Config inventory within a single account. This means that if a CNAME record in Account A points to a resource that legitimately exists in Account B within the same AWS organization, the rule will flag it as NON_COMPLIANT.
For organizations that share resources across accounts, you can modify the solution to use an AWS Config Aggregator, which queries resource inventory across all accounts in your organization. This is similar to how IAM Access Analyzer supports both account-level and organization-level scopes. To use this approach, you need an organization-level Config Aggregator already configured, and the Lambda function’s IAM role needs the config:SelectAggregateResourceConfig permission.
We recommend starting with account-level scope for simplicity, then expanding to organization-level if your environment includes cross-account resource sharing.
The main idea is to create a custom AWS Config rule that queries your Route 53 hosted zones for CNAME records, then parses each CNAME target to determine whether it points to a known AWS resource pattern such as S3, CloudFront, or Elastic Beanstalk. For each match, the rule cross-references the target against your AWS Config inventory to verify that the resource actually exists in your account. If the resource isn’t found, the rule marks the CNAME record as NON_COMPLIANT, surfacing it for review.
The Config rule should focus on known AWS resource patterns:
Note: CNAME records pointing to external third-party services are outside the scope of this detection mechanism, as those resources won’t appear in your AWS Config inventory.
NON_COMPLIANT findings from your Config rule can be routed to AWS Security Hub for centralized visibility, or trigger SNS notifications to alert your security team.
Figure 5: Dangling DNS Detection Solution
Reference implementation:
We’ve published a complete implementation of this detection approach as an open-source solution. The solution deploys a Lambda function that discovers CNAME records across all your Route 53 hosted zones and uses pattern matching to identify targets pointing to S3, CloudFront, and Elastic Beanstalk. It then queries your AWS Config inventory to verify whether each target resource still exists in your account. When a dangling record is detected, the solution generates a HIGH severity finding in Security Hub and can optionally send SNS notifications to alert your security team. A CloudWatch metrics dashboard is also included for ongoing compliance tracking.
Deployment:
# Clone the repository
git clone https://github.com/aws-samples/sample-dangling-dns-detection
cd sample-dangling-dns-detection

# Build the Lambda deployment package
./scripts/package.sh

# Upload to S3
aws s3 cp dist/dangling-dns-detection.zip s3://YOUR_BUCKET/

# Deploy the CloudFormation stack
aws cloudformation deploy \
  --template-file infrastructure/template.yaml \
  --stack-name dangling-dns-detection \
  --parameter-overrides \
      LambdaCodeS3Bucket=YOUR_BUCKET \
      EvaluationFrequency=TwentyFour_Hours \
  --capabilities CAPABILITY_NAMED_IAM
The stack creates an AWS Config custom rule that runs on your specified schedule (default: every 24 hours), evaluating all CNAME records and reporting compliance status.
Mitigating the effects
Mitigating subdomain takeover requires both preventive procedures and responsive capabilities.
Prevention: Standard operating procedure
The most effective mitigation is a standard operating procedure for resource deprovisioning that ensures DNS records are removed before the underlying resource:
Within your DNS zone, delete the CNAME record that points to the fully qualified domain name (FQDN) of the resource that you plan to deprovision.
Wait for the DNS TTL to expire before deleting the resource. DNS resolvers cache records for the duration of the TTL (for example, a TTL of 3600 means resolvers may serve the old record for up to one hour). If you delete the resource before the TTL expires, a threat actor could claim the resource name while cached CNAME entries are still directing traffic to it.
Deprovision the resource that you no longer want to use.
Run a DNS check of the CNAME record that you removed to verify that the resource is no longer resolving.
Key principle: Always delete DNS first, wait for the TTL to expire, then delete the resource. This order eliminates the window where a dangling record could be exploited.
Prevention: S3 account regional namespaces
As mentioned earlier, AWS introduced account regional namespaces for Amazon S3 general purpose buckets in March 2026. While this is a meaningful step toward mitigating the S3-specific takeover vector, there are important operational limitations to be aware of:
Existing buckets are unaffected. Buckets already created in the global namespace cannot be migrated to an account regional namespace. The bucket names remain globally unique and claimable by anyone if the bucket is deleted.
Global namespace is still the default. When creating a new bucket through the console, CLI, or SDK, the global namespace remains the default selection. Users who aren’t aware of the new option will continue creating globally-scoped buckets.
Existing IaC templates require updates. Existing infrastructure-as-code templates (CloudFormation, CDK, Terraform) that don’t explicitly opt in to the account regional namespace will continue provisioning buckets in the global namespace. For CloudFormation, this means setting the BucketNamespace property to account-regional. For other IaC tools, consult their documentation for the equivalent configuration. Organizations need to audit and update their templates to opt in.
For these reasons, the dangling DNS detection approach described in this post remains critical – particularly for organizations with existing S3 infrastructure, and for CloudFront, and Elastic Beanstalk resources where no equivalent namespace scoping exists.
Response: Notification and remediation
When a dangling DNS record is detected, the reference solution described in the Detection section automatically creates a HIGH severity finding in AWS Security Hub and reports the CNAME record as NON_COMPLIANT in AWS Config. If you provide an SNS topic ARN during deployment, the solution also sends notifications to alert your security or operations team via email, Slack, or other channels. For production environments, consider a human-in-the-loop workflow where these notifications are reviewed by a team member who approves the DNS record deletion before it’s executed. This prevents accidental deletion of legitimate records during transient issues.
The reference solution also includes a CloudWatch dashboard for tracking compliance status and evaluation metrics over time, giving your team ongoing visibility into DNS health across your hosted zones.
Note: Fully automated remediation (auto-deleting DNS records) carries risk – a false positive could disrupt legitimate services. We recommend starting with detection and notification, then evaluating automation based on your detection accuracy and operational maturity.
Conclusion
Subdomain takeover is a preventable misconfiguration that can have significant impact on your organization. A layered defense approach provides the best protection:
Prevention: Implement a standard operating procedure that deletes DNS records before deprovisioning the underlying resource.
Detection: Use AWS Config custom rules to proactively identify CNAME records pointing to resources that no longer exist in your account.
Response: Configure notifications through SNS or Security Hub so your team can respond quickly when dangling records are detected.
Monitoring: Maintain ongoing visibility through CloudWatch dashboards to track DNS health and compliance status.
The key insight is that good DNS hygiene – knowing when your CNAME records point to a nonexistent resource – is your first line of defense. Automated detection through AWS Config provides a safety net when operational procedures fail. And if you detect an issue, having a playbook ready to enact your response can lower the impact and your mean time to recovery.
If you have feedback about this post, submit comments in the Comments section below.
This post is co-authored with Sathish Kumar and Christopher Chan from Samsung ecommerce.
In high-traffic ecommerce, achieving real-time pricing is critical to prevent price inconsistency. Pricing inconsistency creates cart shock and erodes trust. This isn’t broken software, it’s a symptom of architectural latency that you can address using AWS Lambda Response Streaming and Amazon CloudFront for systems aggregating data from multiple backend sources.
In this post, we walk through the legacy architecture challenges, the stateless streaming solution, key implementation patterns, and performance results—a pattern you can apply if you’re building high-traffic APIs that aggregate data from multiple backend sources.
Samsung.com is Samsung’s primary direct-to-consumer channel, selling smartphones, TVs, appliances, and accessories, each with multiple variants, offers, and regional pricing. This complexity makes real-time price accuracy especially important.
Samsung’s All Deals and Product Finder pages showcase these products during high-traffic events like Black Friday. To maintain low latency for these high-density Product Listing Pages (PLPs) and comparison tables, the legacy infrastructure relied on asynchronous caching, which introduced a desynchronization gap where the cached price drifted from the authoritative pricing engine.
Problem: Legacy middleware caching created a 1-hour desynchronization gap between the authoritative pricing engine and customer-facing pages.
Our approach: We dismantled the stateful Data Aggregation (DA) architecture and built a real-time Bulk Arbitration Engine (a stateless orchestration layer that queries the Pricing Engine directly at request time) using AWS Lambda Response Streaming and Amazon CloudFront edge caching.
Challenge: The Data Aggregation trap
When product listing pages need to display pricing for over 30 item combinations simultaneously, the latency of calling the Pricing Engine for each item combination individually becomes untenable. To solve this, we built a backend for frontend (BFF) service to do a “Data Aggregation. This DA service was designed to decouple the frontend from the heavy Pricing Engine.
It relied on a scheduled Cron Worker that ran hourly to fetch the entire product catalog. The worker would then precompute prices for every possible permutation of products and store them in a local cache.
While this improved read speeds, it created two significant failures:
1. The Permutation Explosion – The DA service had to precompute every combination just in case a customer viewed it.
The Math: 30 products × (Variants × Offers × Add-ons) = Thousands of records per page
Storage Impact: Cache grew exponentially with each new product variant added
Waste: Most precomputed combinations were never requested
2. The Synchronization Lag – Because the Cron job ran only once per hour, price changes (for example, flash sales) lagged significantly. Customers continued to see old prices until the next scheduled sync.
Business Impact: Flash sales showed incorrect old pricing until the next run time
Customer Trust: Cart shock when checkout price differed from product page price
Competitive Disadvantage: Competitors with real-time pricing gained market share
Legacy Data Aggregation architecture
Architecture diagram showing the legacy Data Aggregation layer between the Pricing Engine and CloudFront CDN.
Figure 1: Legacy Data Aggregation (DA) ArchitectureThe legacy system relied on a scheduled Cron job, creating a distinct “Desynchronization Layer” between the Authority (Pricing) and the Customer. Precomputation of all product permutations consumed significant storage and compute resources.
The solution: Stateless streaming architecture
Intermediate layers storing data will eventually diverge from the source, so we collaborated with our AWS Technical Account Manager (TAM) and service teams to architect a new solution: the Bulk Arbitration Engine, a stateless orchestration layer that queries the Pricing Engine directly at request time.
The new architecture follows a Pass-Through pattern:
1. Client Request: The browser requests prices for 30 specific SKUs using a single HTTP GET request.
2. Streaming Orchestration: An AWS Lambda function fans out these 30 requests to the Pricing Engine in parallel.
3. Immediate Response: As the Pricing Engine returns data, the Lambda streams it immediately to the client without buffering.
Why Lambda Response Streaming?
We evaluated several alternatives before settling on this approach:
Traditional request-response pattern (buffered) – A standard Lambda invocation buffers the full response before returning it to the client, which negates the latency benefit of parallel fan-out. For 30 concurrent SKU lookups, this added seconds of wait time.
EC2 with improved caching – This was the legacy approach. Caching layers will eventually drift from the source of truth, which was the core problem we needed to solve.
Lambda Response Streaming – This was the only option that let us fan out requests in parallel, stream results as they arrived (reducing time-to-first-byte), and remain fully stateless with no intermediate cache to maintain or invalidate.
New stateless streaming architecture
Architecture diagram showing the stateless streaming solution with CloudFront connected directly to Lambda.
Figure 2: Stateless Streaming ArchitectureThe new architecture eliminates the middleware cache. A high-performance stream connects the user directly to the pricing source of truth. CloudFront edge locations cache the response for 95% of traffic, while remaining requests go directly to Lambda for real-time pricing.
Implementation walkthrough
Transitioning to this new architecture required solving two specific technical constraints regarding CDN behavior and cold starts. We implemented the solution in three steps.
Step 1: Implementing the streaming handler
The core of our solution is the Node.js Lambda handler wrapped in awslambda.streamifyResponse(). This allows us to pipe data through a transformation and compression stream directly to the client as it becomes available.
We used a custom NDJSONTransform to convert pricing objects into newline-delimited JSON (NDJSON), allowing the browser to parse and render each price as it arrives rather than waiting for the complete response.
// Lambda Handler with Response Streaming
// File: lambda-handler.js

import * as awslambda from "aws-lambda";
import * as zlib from "zlib";
import { pipeline } from "stream/promises";
import { NDJSONTransform } from "./transforms/ndjson-transform.js";

// Constants
const PROCESSING_MODE = process.env.PROCESSING_MODE || "MODE_QUERYSTRING";
const MODE_QUERYSTRING = "MODE_QUERYSTRING";

// The Handler MUST be wrapped in streamifyResponse() to enable streaming
export const handler = awslambda.streamifyResponse(
  async (event, responseStream, _context) => {
    try {
      if (PROCESSING_MODE === MODE_QUERYSTRING) {
        // Set response metadata with status code and headers
        const httpResponseMetadata = {
          statusCode: 200,
          headers: {
            "Content-Type": "application/x-ndjson",
            "Content-Encoding": "gzip",
            "Cache-Control": "public, max-age=300", // 5 min cache
            "X-Custom-Header": "lambda-streaming",
          },
        };

        responseStream = awslambda.HttpResponseStream.from(
          responseStream,
          httpResponseMetadata
        );

        const ndjsonTransform = new NDJSONTransform();

        // Create gzip stream with fast compression level (Z_BEST_SPEED = Level 1)
        // Level 1 prioritizes speed over compression ratio for real-time responses
        const gzip = zlib.createGzip({
          level: zlib.constants.Z_BEST_SPEED,
        });

        // Process the request, writing to the gzip stream
        await processRequestUsingQueryString(event, ndjsonTransform, _context);

        // Pipeline: Transform → Compress → Send
        await pipeline(ndjsonTransform, gzip, responseStream);
      }

      // ... error handling
    } catch (error) {
      console.error("Lambda streaming error:", error);
      responseStream.destroy();
    } finally {
      await flushMetrics().catch(console.error);
    }
  }
);
Helper function to fan-out the requests in parallel:
// Process request: fan out SKU lookups in parallel
async function processRequestUsingQueryString(event, ndjsonTransform, context) {
  try {
    // Parse query string to extract SKU list
    const queryString = event.rawQueryString || "";
    const skus = parseCompressedQueryString(queryString);

    // Fetch pricing in parallel using Promise.all
    const pricingPromises = skus.map((sku) =>
      fetchPricingForSKU(sku).catch((err) => ({
        sku: sku.id,
        error: err.message,
      }))
    );

    const pricingResults = await Promise.all(pricingPromises);

    // Emit each result as a separate NDJSON line
    for (const result of pricingResults) {
      ndjsonTransform.write(result);
    }

    ndjsonTransform.end();
  } catch (error) {
    ndjsonTransform.destroy(error);
  }
}
The handler also uses helper functions for parsing the compressed query string (parseCompressedQueryString), fetching individual SKU prices with connection pooling (fetchPricingForSKU), and flushing metrics to Amazon CloudWatch (flushMetrics).
Key implementation details:
awslambda.streamifyResponse() wraps the handler so it streams data in real time instead of waiting for the full response from the pricing engine.
NDJSONTransform converts objects to newline-delimited JSON (one object per line)
GZIP (GNU zip) compression with Z_BEST_SPEED (Level 1) prioritizes speed over compression ratio
pipeline() handles error propagation and stream cleanup
Response headers include Cache-Control for CloudFront caching
Step 2: Compressing the request data into a GET request
We needed to send complex request data (30 SKUs, context metadata) to the API.
Constraint: CloudFront and standard HTTP specs treat POST requests as non-idempotent, meaning they are not cacheable by default.
Our approach: We developed a dense, compressed query string format to fit the complex request data into a standard GET request. Format: g=group1(p=SKU-A:1:p=SKU-B:2)…
This allowed us to strictly use GET requests, keeping the request URI within standard length limits (~800 bytes) while carrying the same data as a 3-4KB JSON body.
Client-Side Code: Building the Compressed Query String
// Client-side: Building the compressed query string format
// File: pricing-client.js

/**
 * Builds a compressed query string for bulk pricing requests
 * Format: g=group1(p=SKU-A:1:p=SKU-B:2:p=SKU-C:3)
 * @param {Array} skus - Array of SKU objects with { id, variant }
 * @param {Object} context - Customer context { customerId, region, sessionId }
 * @returns {string} Compressed query string
 */
function buildPricingQueryString(skus, context = {}) {
  if (!skus || skus.length === 0) {
    throw new Error("SKUs array cannot be empty");
  }

  if (skus.length > 30) {
    throw new Error("Maximum 30 SKUs per request. Split into multiple batches.");
  }

  // Build SKU portion: p=SKU-001:1:p=SKU-002:2
  const skuParts = skus
    .map((sku) => {
      const variant = sku.variant || 1;
      return `p=${sku.id}:${variant}`;
    })
    .join(":");

  // Build context portion (optional)
  let contextPart = "";
  if (context && Object.keys(context).length > 0) {
    const contextStr = Object.entries(context)
      .map(([key, value]) => `${key}=${value}`)
      .join(":");
    contextPart = `:c=${contextStr}`;
  }

  // Final format: g=group1(p=SKU-A:1:p=SKU-B:2:c=customerId=123:region=US-EAST-1)
  return `g=group1(${skuParts}${contextPart})`;
}

/**
 * Fetches pricing data with streaming NDJSON response parsing
 * Core pattern: read chunks, split by newlines, parse each line as JSON
 */
async function fetchPricingStream(skus, options = {}) {
  const queryString = buildPricingQueryString(skus);
  const url = `${options.baseUrl}?${queryString}`;
  const response = await fetch(url, {
    method: "GET",
    headers: { Accept: "application/x-ndjson" },
  });

  // Stream the response using the ReadableStream API
  const reader = response.body.getReader();
  const decoder = new TextDecoder();
  const pricingData = [];
  let buffer = "";

  while (true) {
    const { done, value } = await reader.read();
    if (done) break;

    // Decode chunk and append to buffer
    buffer += decoder.decode(value, { stream: true });

    // Split by newlines (NDJSON format: one JSON object per line)
    const lines = buffer.split("\n");

    // Keep the last incomplete line in buffer
    buffer = lines.pop() || "";

    // Parse each complete line as a JSON object
    for (const line of lines) {
      if (line.trim()) {
        const pricingObject = JSON.parse(line);
        pricingData.push(pricingObject);

        // Optional: update UI immediately as each price arrives
        if (options.onChunk) {
          options.onChunk(pricingObject);
        }
      }
    }
  }

  reader.releaseLock();
  return pricingData;
}
On page load, the client calls fetchPricingStream with up to 30 SKUs and an onChunk callback that updates each product’s DOM (Document Object Model) element as pricing chunks arrive. Helper functions handle updating individual price elements, displaying variant information, and gracefully degrading with a user-friendly message if pricing is temporarily unavailable.
Step 3: Configuring CloudFront for uncacheable requests
To allow CloudFront to cache these complex GET requests effectively, we configured a precise Cache Policy that includes all query strings and specific headers.
The CloudFront distribution itself is configured with HTTPS-only viewer protocol, the cache policy and origin request policy as shown in the preceding section, and points to the Lambda as its origin through HTTPS.
Cache policy highlights:
5-minute default TTL balances freshness and cache efficiency
Query strings included in cache key (different SKU combos = separate cache entries)
5–30 minute TTL range provides flexibility for different content
Performance optimization results
We optimized the system through four distinct phases, testing each configuration with K6 load test scripts (500 concurrent users, 30 items per request) to simulate high-traffic events like Black Friday.
Phase 1: The baseline (Global VPN)
We tested our initial proof-of-concept with the default network configuration, where all outbound traffic (including requests to AWS services like Lambda) was routed through a global VPN, forcing traffic onto the public network and back into the AWS backbone, adding unnecessary network hops and delays. The Lambda used a standard buffered response with no compression. The results were suboptimal (4,500ms P90) because connection overhead dominated the request.
DNS resolution: approximately 50 ms
TCP handshake: approximately 100 ms
TLS negotiation: approximately 150 ms
Total connection overhead: approximately 300 ms per call
This overhead created a massive bottleneck for latency before business logic even ran.
Phase 2: Amazon VPC Peering and warm starts
To remove the network penalty, we acted on two fronts:
First: Moved the Lambda inside an Amazon Virtual Private Cloud (Amazon VPC) peered directly to the pricing origin, cutting DNS and TLS overhead to near zero for internal calls.
Second: Enabled Provisioned Concurrency for Lambda to remove the 500–1000 ms cold start latency.
With these changes, P90 latency dropped to 1,000 ms, a 4.5x improvement, but still not real-time enough.
Phase 3: HTTP/2 and GZIP compression
The remaining bottleneck was the sheer size of the data transfer. We targeted two optimizations:
HTTP/2 Multiplexing: Enabled HTTP/2 multiplexing to reuse a single TCP connection for the 30 parallel SKU lookups, saving seconds of cumulative handshake time.
GZIP Compression: Applied GZIP compression (Level 1 / Z_BEST_SPEED), which reduced the response size by 76 percent (170KB → 40KB).
These two optimizations brought P90 latency down to 218 ms.
Phase 4: Production (edge caching)
In the final phase, we layered CloudFront edge caching on top of the optimized Lambda. Because we had successfully converted our request data to a GET request (Step 2), we could now cache the computed prices for 95 percent of incoming traffic.The final P90 latency landed at 50 ms.In practice, the 95 percent cache hit ratio means only 1 in 20 requests actually invokes the Lambda function; the rest are served directly from CloudFront edge locations closest to the customer. During peak events like Black Friday, this translates to millions of requests served at edge speed without touching the origin, keeping both latency and compute costs minimal.
Performance metrics table
Metric
Phase 1 (Baseline)
Phase 2 (VPC)
Phase 3 (HTTP/2)
Phase 4 (Production)
P50 Latency
1,670 ms
501 ms
176 ms
35 ms
P90 Latency
4,500 ms
1,000 ms
218 ms
50 ms
P99 Latency
5,100 ms
2,400 ms
500 ms
150 ms
Cache Hit Ratio
<1%
<1%
<1%
95%
Response Size
170 KB
170 KB
40 KB
40 KB
Concurrent Users
500
500
500
500
P90 Improvement vs Baseline
1x
4.5x
20x
90x
The following chart shows P90 latency improvements across each optimization phase.
Latency improvements across four optimization phases.
K6 load test configuration:
// A sample K6 load test script
import http from 'k6/http';
import { check } from 'k6';

export let options = {
  stages: [
    { duration: '2m', target: 100 },  // Ramp up
    { duration: '5m', target: 500 },  // Stay at 500 concurrent users
    { duration: '2m', target: 0 },    // Ramp down
  ],
  thresholds: {
    http_req_duration: ['p(90)<100', 'p(99)<500'], // P90 < 100ms, P99 < 500ms
  },
};

export default function () {
  const url = 'https://api.example.com/pricing?g=group1(p=SKU-001:1:p=SKU-002:2:...)';
  const res = http.get(url);

  check(res, {
    'status is 200': (r) => r.status === 200,
    'response has content': (r) => r.body.length > 0,
  });
}
Resilience, scale, and security considerations
Beyond latency, we designed the system to handle failure gracefully, scale under load, and protect data in transit.
Batching limits
The 30-item limit per request is intentional. If a page requires more (for example, 50 items), the client logic splits them into multiple parallel batches.–We chose 30 because of the following:
Lambda execution time under 5 seconds
Prevents timeout issues during high latency
Balances parallel requests vs. Lambda concurrency limits
Typical product listing pages show 20–30 items
async function fetchLargePricingBatch(skus) {
  const BATCH_SIZE = 30;
  const batches = [];

  // Split into 30-item chunks
  for (let i = 0; i < skus.length; i += BATCH_SIZE) {
    batches.push(skus.slice(i, i + BATCH_SIZE));
  }

  // Fetch all batches in parallel
  const results = await Promise.all(
    batches.map((batch) =>
      fetchPricingStream(batch, { timeout: 30000 })
    )
  );

  // Flatten results
  return results.flat();
}
Partial failures
The streaming architecture is resilient. If pricing for one item fails, the stream doesn’t crash; it continues processing the remaining items, so the user still sees a mostly complete page.
Partial failure handling:
async function processRequestUsingQueryString(event, ndjsonTransform, context) {
  const skus = parseCompressedQueryString(event.rawQueryString);

  for (const sku of skus) {
    try {
      const pricing = await fetchPricingForSKU(sku);
      ndjsonTransform.write(pricing);
    } catch (error) {
      // Emit error object but continue processing other SKUs
      ndjsonTransform.write({
        sku: sku.id,
        variant: sku.variant,
        error: error.message,
        timestamp: new Date().toISOString(),
      });
    }
  }

  ndjsonTransform.end();
}
Data protection
While constructing the query string on the client exposes the request structure, this data (SKUs, variants) is already public. The actual pricing logic and business rules remain securely protected within the Pricing Engine.
Data in transit encrypted with TLS 1.3.
Amazon VPC endpoint connection to pricing engine (no internet exposure).
No sensitive data logged (PII, pricing algorithms excluded).
Stale pricing forces engineering teams to choose between freshness and scale. With the Data Aggregation pattern, we attempted to maintain both but compromised on data integrity due to the lag inherent in scheduled synchronization.By using AWS Lambda Response Streaming and Amazon CloudFront, we removed the need for a synchronization layer entirely. The result is a system that delivers the 50 ms latency required for a smooth user experience while supporting price consistency between the product page and checkout.
Beyond performance, this architecture significantly reduced operational footprint: compute fleet shrank from over 100 auto-scaled instances during peak events to only 5–10 Lambda functions, lowering maintenance and operational costs. This outcome was the result of close collaboration between Samsung’s ecommerce engineering team, our AWS Technical Account Manager (TAM), and the Lambda and CloudFront service teams, who helped architect the solution, review design decisions, and guide Samsung through production readiness. This technique applies to similar high-traffic data aggregation scenarios: product catalogs, inventory systems, recommendation engines, or services that combine multiple backend responses in real-time.
To get started, identify your highest-latency aggregation endpoints, evaluate whether your request data can be converted to cacheable GET requests and implement Lambda Response Streaming for a single endpoint before migrating your full API
When something breaks in production, you find out fast. Understanding why it broke, before the damage spreads, is the hard part. That is where Site Reliability Engineering (SRE) teams lose the most time.
Think about the last time you got paged at 2 a.m. The alert said something broke, not why. You open four or five dashboards, cross-reference deployment logs with AWS CloudTrail events, and scroll through metrics. Twenty or thirty minutes burn before the picture comes together. That manual correlation is where resolution time balloons.
What if the investigation started before you opened your first dashboard?
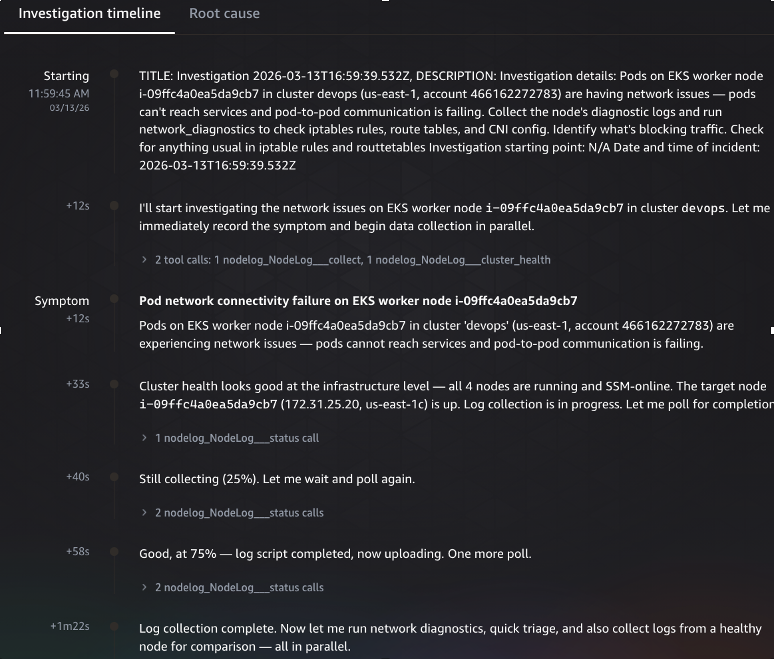
That’s the idea behind connecting the new native PagerDuty Capability Provider in AWS DevOps Agent. The two systems now talk directly over a built-in OAuth 2.0 connection. When a PagerDuty incident triggers, the DevOps Agent starts investigating while responders are still getting oriented. Connecting them takes a few fields in a console.
What AWS DevOps Agent does
AWS DevOps Agent is a frontier agent built to help engineering teams investigate and resolve production incidents faster. The DevOps Agent works as a first responder, conducting federated investigations across your observability stack, tracing incidents from code changes all the way through to cloud infrastructure impact, and producing detailed mitigation plans. Beyond reactive investigations, it also proactively recommends improvements to your observability, infrastructure, and deployment pipelines to help prevent recurring issues. Through the AWS DevOps Agent web app, you can observe investigations as they unfold, access findings, and steer the analysis in real time.
The central concept is the Agent Space. Think of it as the boundary that defines what your agent can access. Your AWS account serves as the primary source, and from there you layer on secondary capabilities from telemetry providers like Datadog, Dynatrace, New Relic, or Splunk; pipeline tools like GitHub and GitLab; communications from PagerDuty and Slack; and custom Model Context Protocol (MCP) servers for anything else. Every investigation the agent runs, it learns. It maps relationships between your resources such as load balancers to services, services to databases, and deployments to config changes. One team we’ve worked with had the agent map hundreds of infrastructure relationships, and that number keeps growing with each investigation it completes.
PagerDuty, of course, needs no introduction to anyone who’s been responsible for resolving critical, customer-impacting incidents. Engineering teams rely on it to detect, triage, resolve, and learn from incidents. The native PagerDuty Capability Provider in AWS DevOps Agent connects the two directly. PagerDuty incident events drive AWS DevOps Agent investigations automatically. Findings flow back to the originating PagerDuty incident record, including root cause analysis and recommended mitigation steps. They are also available in the AWS DevOps Agent console and web app, giving your whole team visibility into what the agent discovered.
There’s a second piece to this integration worth understanding. By adding the PagerDuty MCP Server as a capability and configuring an AWS DevOps Agent skill for working with PagerDuty, you enable AWS DevOps Agent to query PagerDuty’s institutional memory during investigations. This includes past incidents, diagnostics, resolution patterns, and operational context across both AWS and non-AWS environments. This PagerDuty MCP Server-based connection is separate from the Capability Provider event flow and requires its own setup (covered in Step 6 below). The result is investigations informed by both current signals and prior incident history.
Why this matters
These are practical, tangible changes for your team:
Faster time to root cause. When a PagerDuty incident triggers, AWS DevOps Agent kicks off an investigation automatically. No one has to sign in to another tool, step through a wizard, or remember to initiate anything. The investigation is already running by the time you acknowledge your alert.
Real contextual analysis. The agent correlates PagerDuty incident data with Amazon CloudWatch metrics, AWS CloudTrail logs, application topology, and deployment history, plus telemetry from whichever third-party observability providers you’ve connected, like Datadog, Splunk, New Relic, or Dynatrace. It connects dots that would otherwise take humans significant time to even start connecting.
Investigations start when an incident triggers. AWS DevOps Agent automatically conducts the deep-dive investigation behind the scenes. It reports back its root cause analysis and proposed mitigation steps into the originating PagerDuty incident, with a link to the AWS DevOps Agent web app for more details.
Less time playing detective, more time fixing things. That manual data correlation across four or five tools? The agent handles it. Your people can focus on actually resolving the issue instead of building the investigation timeline by hand.
Nothing extra to host. The native PagerDuty Capability Provider means you’re not standing up additional infrastructure. No servers to manage, no endpoints to maintain on your side.
How the integration works
The architecture is straightforward. Here’s the flow:
AWS DevOps Agent and PagerDuty authenticate to each other using OAuth 2.0 Scoped OAuth. You register PagerDuty once at the AWS account level as a Capability Provider, and then add it to whichever Agent Spaces need it. Registration is shared across Agent Spaces in the account, so you don’t have to repeat the setup per team.
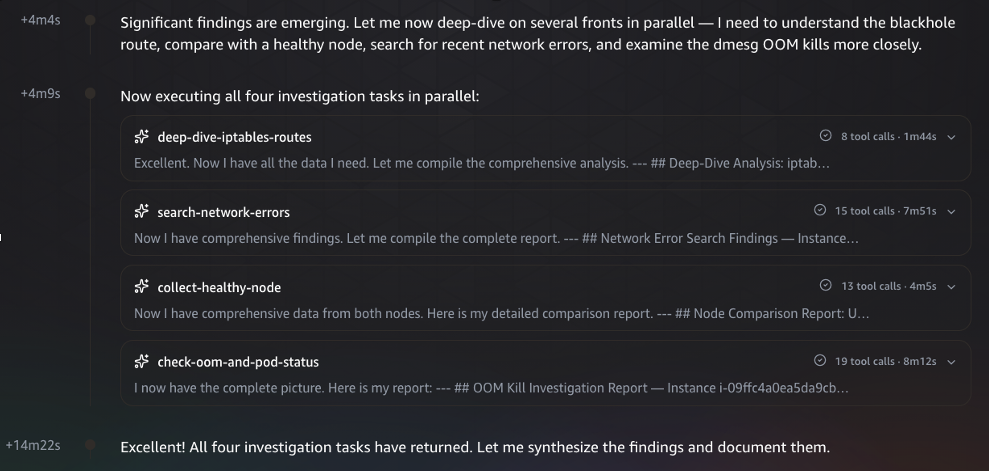
Once a PagerDuty incident triggers, AWS DevOps Agent picks up the event over the native connection and begins investigating:
Receives the PagerDuty incident event (service, severity, and initial context) via the native Capability Provider connection
If the PagerDuty MCP capability and AWS DevOps Agent skill are configured, queries PagerDuty for related historical incidents, past diagnostics, and resolution patterns to enrich the investigation
Examines AWS resource topology and the relationships between your infrastructure components through its knowledge graph
Reviews AWS CloudTrail logs for recent changes or anything that looks off
Queries Amazon CloudWatch and connected telemetry providers (Datadog, Dynatrace, New Relic, Splunk) for relevant metrics and traces
Cross-references deployment events from configured pipeline tools (GitHub, GitLab) against the incident timeline
Synthesizes potential root causes from all the evidence it’s gathered
The agent builds up a comprehensive picture by introspecting AWS observability data, pulling from connected capability providers, and leveraging the topology mapping that creates a knowledge graph of your application infrastructure. Every investigation it runs expands its understanding of how your resources connect. It discovers relationships you might not have explicitly documented, building a richer map with each incident it works.
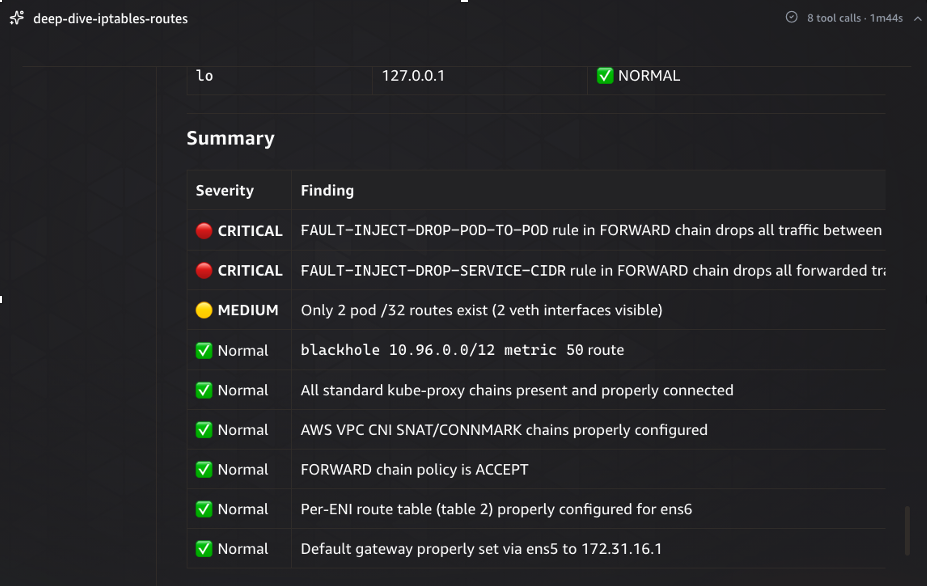
Beyond raw data, the agent produces detailed mitigation plans with specific actions to resolve the issue, validate the fix, and revert if needed. The agent posts its findings, root cause summary, and recommended next steps directly to the originating PagerDuty incident record, giving your on-call team actionable information without them having to go digging.
A quick note on security, because it matters. The native connection uses OAuth 2.0 Scoped OAuth with a minimum set of PagerDuty scopes (incidents.readincidents.writeservices.readwebhook_subscriptions.readwebhook_subscriptions.write). AWS DevOps Agent only supports the newer scoped OAuth flow; legacy PagerDuty OAuth with a redirect URI is not supported. For inbound events from PagerDuty, only V3 webhooks are supported. Earlier webhook versions won’t work. Traffic flows over HTTPS.
Getting it set up
Setup comes in four phases: register PagerDuty as a Capability Provider at the account level, attach it to your Agent Space, configure the PagerDuty MCP server and AWS DevOps Agent skill for working with PagerDuty to enrich investigations, and verify things work end to end.
What you’ll need
An active AWS account with permissions to use AWS DevOps Agent
AWS DevOps Agent enabled in a supported AWS Region. You’ll create an Agent Space, which needs two AWS Identity and Access Management (IAM) roles (one for Agent Space operations, one for web app functionality). Both can be auto-created during setup
A PagerDuty account with permission to register OAuth apps, plus an Administrator role for Events Integration
A PagerDuty Advance license and a PagerDuty User API token (for the MCP integration in Step 6)
Your PagerDuty account subdomain (so if your PagerDuty URL is https://your-company.pagerduty.com, the subdomain is your-company)
An OAuth client ID and client secret from a PagerDuty app registered with OAuth 2.0 Scoped OAuth
Step 1: Create your Agent Space
Stand up an Agent Space in the AWS DevOps Agent console. This defines the boundary for what the agent can reach into and investigate.
Head to the AWS DevOps Agent console home page.
AWS DevOps Agent console home page.
Create a new Agent Space with a name and a short description, usually scoped to a service or application team’s responsibilities
Creating a new Agent Space with a name and description.
Create the Agent Space IAM roles (AWS DevOps Agent requires two IAM roles: one for Agent Space operations and another for its associated web app functionality). You can auto-create them during setup
Configuring the two IAM roles required for the Agent Space.
IAM roles can be auto-created during setup.
Your primary source (the AWS account you’re creating the Agent Space in) is added automatically. If you need the agent to investigate resources in other accounts, add those as secondary sources
The AWS account is added automatically as the primary source.
Step 2: Add supporting capabilities
Out of the box, the agent connects to Amazon CloudWatch for metrics, logs, and alarms, and can investigate AWS CloudTrail API activity and AWS X-Ray traces through its read-only permissions. That said, most teams don’t live entirely inside AWS tooling, and that’s where third-party capability providers pull their weight. You can wire in external tools to give the agent a fuller picture of your world:
Telemetry: Datadog, Dynatrace, New Relic, or Splunk, so the agent can pull metrics and traces beyond Amazon CloudWatch during investigations
Pipelines: GitHub or GitLab, so it can correlate deployments and code changes with incidents
Communications: Slack, for team coordination and investigation updates (PagerDuty is configured separately as a Capability Provider in Step 4)
MCP Servers: Custom integrations via OAuth or API keys for anything else in your stack
You don’t need everything connected on day one. Start with what makes sense and add more as you go. Each new capability helps the agent discover more infrastructure relationships and investigate more effectively.
Step 3: Set up application topology
Help the agent understand what your application landscape looks like:
Configure IAM roles to define the AWS topology scope for your Agent Space. The agent uses these permissions to determine which resources it can see and investigate
Give the agent time to discover and map the relationships between your resources (it does this automatically as it runs investigations)
Check the interactive topology visualization in the console and make sure your critical components are showing up correctly
If you want the agent to focus on certain tags or resource subsets, add those instructions to your skills
Step 4: Register PagerDuty as a Capability Provider
You register PagerDuty once at the AWS account level. From there, it’s shared across every Agent Space in the account.
First, create the OAuth app in PagerDuty:
In a separate browser tab, sign in to PagerDuty and go to Integrations > App Registration
In PagerDuty, navigate to Integrations then App Registration.
PagerDuty App Registration page.
Create a new app using OAuth 2.0 Scoped OAuth. AWS DevOps Agent does not support legacy PagerDuty OAuth with redirect URI
Create the app using OAuth 2.0 Scoped OAuth.
Under Permissions, grant the minimum scopes: incidents.readincidents.writeservices.readwebhook_subscriptions.readwebhook_subscriptions.write
Granting the minimum required OAuth scopes.
Turn on Events Integration so AWS DevOps Agent and PagerDuty can talk in both directions
Turn on Events Integration for two-way communication.
Copy your Client ID and Client Secret. You’ll paste them into the AWS console in a minute
Copy the Client ID and Client Secret from PagerDuty.
Then, register PagerDuty in the AWS DevOps Agent console:
In the AWS DevOps Agent console, open the Capability Providers page from the side navigation
In the Available providers section, find PagerDuty under Communication and choose Register
Find PagerDuty under Communication and choose Register.
On the Configure access in PagerDuty page, pick your PagerDuty region (US or EU) and enter your PagerDuty subdomain (if your PagerDuty URL is https://your-company.pagerduty.com, the subdomain is your-company)
Paste in the OAuth Client name, Client ID, and Client secret from PagerDuty. Confirm the minimum scopes (incidents.readincidents.writeservices.readwebhook_subscriptions.readwebhook_subscriptions.write)
Enter your PagerDuty region, subdomain, and OAuth credentials.
Review the configuration and choose Add
Review the configuration and choose Add.
Once registration goes through, PagerDuty shows up under the Currently registered section of the Capability Providers page.
PagerDuty appears under Currently registered after registration.
Step 5: Add PagerDuty to your Agent Space
PagerDuty is registered at the account level. Now connect it to the Agent Space that needs it:
In the AWS DevOps Agent console, pick your Agent Space
Open the Capabilities tab
In the Communications section, choose Add
On the Capabilities tab, choose Add in the Communications section.
Select PagerDuty from the list of available providers
Select PagerDuty from the list of available providers.
Step 6: Add PagerDuty MCP Server and configure the agent skill
The Capability Provider from the previous steps handles the event flow. When a PagerDuty incident triggers, AWS DevOps Agent investigates and posts findings back to the originating PagerDuty incident. To let the agent also pull context from PagerDuty during those investigations, you add two things: the PagerDuty MCP server as a custom MCP capability, and an AWS DevOps Agent skill for working with PagerDuty that tells the agent when and how to use it.
Prerequisites:
PagerDuty Advance license
A PagerDuty User API token (generate one at User Settings > API Access in PagerDuty)
Add the PagerDuty MCP server:
In your Agent Space, go to Capabilities tab > MCP Servers
Open the MCP Servers section on the Capabilities tab.
Add a new custom MCP server with the following configuration:
Server URL: https://mcp.pagerduty.com/mcp
For EU region PagerDuty accounts, use https://mcp.eu.pagerduty.com/mcp instead
Authentication: PagerDuty User API token in the format Token token=<your-pagerduty-api-key>
Add a new custom MCP server.
Configure the server URL and PagerDuty User API token.
Add the AWS DevOps Agent skill for working with PagerDuty:
The MCP server gives the agent access to PagerDuty tools. The skill tells the agent when and how to use them during investigations.
In your Agent Space, choose Operator access to open the web app in a separate browser window
Choose Operator access to open the web app.
In the Agent Space Operator web app, navigate to Knowledge and the Skills tab, then choose Add skill
On the Skills page, choose Add skill.
You can select Create skill to create a skill through a wizard, interactively chat with the agent to create a skill, or upload a skill zip file if you already have one
Choose how to create the skill.
Choose Create skill and fill out the skill instructions from the table below to create a skill
Fill out the skill instructions.
You should see the pagerduty-aws-devops-agent skill added to the AWS DevOps Agent
The pagerduty-aws-devops-agent skill added to AWS DevOps Agent.
Skill form instructions:
Field
Value
Name
pagerduty-aws-devops-agent
Description
Use this skill to interact with the PagerDuty Advance SRE Agent for incident response, troubleshooting, runbook generation, and log search. Invoke when the agent is investigating incidents, performing triage, root cause analysis, or resolving operational issues. This skill calls the sre_agent_tool from the pagerduty-advance-mcp MCP server to access PagerDuty’s historical incident data, diagnostics, and resolution patterns.
Status
Active
Agent Type
Generic
Instructions
See the skill instructions code block below.
Skill instructions (paste into the Instructions field):
# PagerDuty Advance SRE Agent

Use the PagerDuty MCP Server to call the `sre_agent_tool` for incident response and technical troubleshooting.

## Prerequisites

This skill requires the `pagerduty-advance-mcp` MCP server to be configured in the Agent Space under Capabilities > MCP Servers.

1. Extract the PagerDuty incident ID from the investigation context
2. Call the `sre_agent_tool` from the `pagerduty-advance-mcp` MCP server with:
   - `message`: a natural language question about the incident
   - `incident_id`: the PagerDuty incident ID
3. If follow-up queries are needed, continue calling `sre_agent_tool` with the same `incident_id` and a new `message`. Pass the `session_id` from the previous response to maintain conversation

## Tool Details

- **Tool name:** `sre_agent_tool`
- **MCP Server:** `pagerduty-advance-mcp`
- **Parameters:**
  - `message` (string, required) — natural language question about the incident
  - `incident_id` (string, required) — the PagerDuty incident ID
  - `session_id` (string, optional) — reuse from previous response for conversation continuity

## What the SRE Agent Can Help With

- Active incident analysis, triage, and resolution
- Root cause analysis and technical explanations
- Incident summaries and catch-ups
- Status updates for stakeholders
- Diagnostic checks and remediation recommendations
- Log interpretation and troubleshooting guidance
- Alert trigger analysis and explanations
- Change event analysis and impact assessment
- Playbook and runbook generation
- Past incident correlation and pattern recognition
- Service dependencies and related system analysis
- Real-time incident monitoring and alerting questions
Step 7: Test and validate
Before you call it finished, confirm things work end to end:
Create a test incident in PagerDuty
Confirm AWS DevOps Agent picks up the event and starts an investigation
Watch the investigation move along in the AWS DevOps Agent console or web app
Review the root cause summary, the mitigation plan, and the investigation findings
Verify that root cause analysis and mitigation steps appear on the originating PagerDuty incident record. If you’ve also connected Slack, check that updates land in your configured channel
Start with a limited scope for your initial Agent Space. Focus on a single application or service first. Get comfortable with the integration, tune your configuration, and then expand from there.
Troubleshooting
A handful of things we’ve seen trip people up:
Registration fails with invalid credentials. Double-check that the Client ID and Client secret were copied from the right PagerDuty OAuth 2.0 Scoped OAuth app. Legacy PagerDuty OAuth apps (the ones configured with a redirect URI) aren’t supported. When credentials do need to change, deregister from the Capability Providers page and re-register with the new values, rather than trying to edit in place.
Webhook events don’t trigger an investigation. AWS DevOps Agent only supports PagerDuty V3 webhooks. If your PagerDuty subscription is still on an older webhook version, upgrade to V3. Full details live in Webhooks Overview in the PagerDuty developer documentation.
PagerDuty shows as registered, but isn’t active in an Agent Space. Registering at the account level and adding the provider to an Agent Space are two separate actions. On the Agent Space’s Capabilities tab, check that PagerDuty appears under Communications. If it doesn’t, add it there.
Region or subdomain mismatch. If your PagerDuty account is on the EU service region, make sure you picked EU during registration. The subdomain has to match the first label of your PagerDuty URL exactly (for example, your-company from https://your-company.pagerduty.com).
Conclusion
Most of what happens in the first several minutes of incident response is undifferentiated heavy lifting like opening dashboards, tailing logs, correlating deployments with AWS CloudTrail events. With the native PagerDuty Capability Provider in AWS DevOps Agent, investigations automatically begin by the time you’ve acknowledged your alert, giving your engineers a head start on root cause analysis before responders have finished triaging.
Shan is a Senior Partner Solutions Architect specializing in generative AI at AWS, dedicated to solving complex user challenges. He advocates for innovative AI solutions, distributed architecture, and serverless technologies, helping users harness the power of generative AI in their cloud journey. You can reach him on LinkedIn.
Laith Al-Saadoon
Laith Al-Saadoon is a Principal AI Engineer at AWS. He created and launched AWS MCP Servers (30M+ PyPI downloads) and contributes to Strands Agents SDK — AWS’s open-source framework for building AI agents — along with other agentic AI open-source projects like Mem0 and Agno. He drives AWS’s autonomous software development and agentic AI strategy and builds production agentic systems that make agents work for the world’s largest companies. In his personal time, Laith enjoys the outdoors — fishing, photography, drone flights, and hiking with his wife.
Scott Schreckengaust
Scott Schreckengaust brings a biomedical engineering degree and decades of deep domain expertise in healthcare and life sciences to emerging technologies and AI. He’s spent his career building—from automating lab workflows and integrating enterprise systems to architecting full-stack software deployments in regulated environments. Now working as an AI engineer, Scott continues what he’s always done best: partner with customers to uncover their scientific and operational challenges, then engineer solutions that scale. His journey from the bench to the cloud reflects a consistent belief: the best technology is invisible—it just works.
Data scientists and ML engineers often need to access raw data files in Amazon Simple Storage Service (Amazon S3) for machine learning training, data exploration, and generative AI workflows. However, when table-level access is governed by AWS Lake Formation, accessing the underlying S3 files has required maintaining separate permission mechanisms. S3 bucket policies or AWS Identity and Access Management (IAM) role policies create operational overhead and risk of permission drift.
Lake Formation now supports direct access to S3 data file locations for tables whose permissions it manages. Previously, data scientists with Lake Formation permissions on AWS Glue Data Catalog tables could query them using spark.sql(). Now, they can also read and write the underlying S3 data files using spark.read.parquet() or spark.read.csv() from Amazon EMR Spark jobs, Amazon SageMaker Unified Studio notebooks with EMR compute, and custom applications. All access is governed by the same Lake Formation permissions.
This capability is powered by the new GetTemporaryDataLocationCredentials() API, which vends temporary credentials scoped to registered S3 locations when callers have appropriate Lake Formation permissions on the corresponding Data Catalog tables. This eliminates the need to manage separate S3 bucket policies for file-level access while maintaining fine-grained access control in Lake Formation for table-based access. It enables your data scientists to explore S3 datasets securely, accelerate machine learning pipelines, and build generative AI workflows without compromising governance.
In this post, we demonstrate reading from and writing to Lake Formation-managed S3 locations using Apache Spark jobs from EMR. Lake Formation credential vending for S3 location access is available in EMR release label 7.13 and later, Boto3 1.42.29 and later, AWS Java SDK 2.41.32 and later, and AWS Command Line Interface (AWS CLI) version 2.33.1 and later.
Key use cases for Lake Formation permissions to S3 locations
Unified permissions for Analytics and Machine Learning pipelines – Data scientists can access both structured tables through SQL queries and underlying data files through programmatic APIs for machine learning and AI workloads. They are empowered to use tools of their choice – for example, use Amazon Athena for SQL analytics with the table names while read and write to the underlying files in their SageMaker notebook or Spark application with spark.read.parquet(“s3://bucket/database_path/table_files/).
Enable AI ready data lakes – Machine learning pipelines can read training data directly from governed data lakes. Generative AI applications can access foundation model training datasets, and data exploration workflows to use native file APIs while maintaining centralized governance and compliance.
Reduced operational complexity – Operations teams don’t need to maintain separate permission policies – one in Lake Formation for table access and another in S3 bucket policies or AWS Identity and Access Management (IAM) roles for file access. This reduces the risk of permission mismatches and avoids inconsistent access control.
Unified audit capability – Auditors do not need to examine multiple log sources, such as S3 Access Logs, AWS CloudTrail events from different services, to understand who accessed what data and when. With this feature, you get a unified CloudTrail audit trail showing both table access through SQL engines and file access through direct APIs, with each access event linked to the Lake Formation permission grant.
What customers are saying
“Through our close collaboration with AWS, Lake Formation’s new S3 location-based permissions have transformed how we manage data governance at Intuit. By unifying two separate access mechanisms for the same data into one unified permission model, we’ve dramatically reduced complexity and streamlined our auditing process. This is exactly the kind of simplification that lets our teams move faster without compromising security, ensuring we maintain the strict compliance and governance standards our regulators expect.”
— Tapan Upadhyay, Group Engineering Manager, Intuit
Lake Formation Credential Vending Plugin for AWS SDK v2 for Java
Lake Formation has made available a specialized library AWS Lake Formation Credential Vending Plugin for AWS SDK V2 for Java. The Java plugin intercepts S3 requests for data, checks Lake Formation permissions for the requested location, and provides temporary scoped credentials to the client if permissions are granted in Lake Formation. If the S3 location access permissions are not managed by Lake Formation, the plugin checks for access in Amazon S3 Access Grants and lastly falls back to IAM permissions. The plugin is supported independently of Spark and comes as an enhancement to EMR Spark Full Table Access (FTA) mode, starting in EMR 7.13 and later. The plugin is integrated at the S3A level. Therefore, any client of S3A can enable it by setting the S3A configurations, in addition to the EMR Lake Formation Full Table Access (FTA) configuration as follows:
With the Java plugin, you can enable governance for data lake resources in your custom applications with Lake Formation permissions – managing both fine grained access for users requiring restricted access on Data Catalog tables while providing direct S3 object level access to use-cases that require them.
Note: (1) The principal that will be accessing direct S3 locations of the tables will require full table access. That is, Lake Formation SELECT permission on all columns and rows of the table is required. (2) The Spark cluster needs FTA configuration. (3) Currently, Apache Iceberg table format is not supported with this plugin.
Solution overview
A financial services company runs daily ETL jobs using Spark in EMR. They process raw transaction records in S3 and store the processed records in another S3 location. The transformed Parquet data is registered with Lake Formation and cataloged as a table in Data Catalog. The ETL job will have direct IAM access to the raw data location, while it uses Lake Formation permissions to write to and read from the curated table location. Downstream, a data-analyst role will query the curated table, with restricted column access. The solution is shown in Figure 1.
Figure 1 – Architecture shows EMR Spark writing curated records to the S3 location of a table using Lake Formation permissions while Data-Analyst queries the same table with Lake Formation fine grained access control in Athena.
Prerequisites
To get started exploring this feature, we recommend you have the following setup.
To run the Spark code in EMR, you can choose to run the code in either SageMaker Unified Studio with EMR compute or use EMR cluster from EMR console. In the case of SageMaker Unified Studio domain and project, the Lake Formation permissions for the table location will be granted to the project execution role. In this post, we will illustrate using an EMR on EC2 cluster and a runtime role to submit the Spark script as a step to the cluster. For instructions to launch an EMR on EC2 cluster with Lake Formation full table access enabled, refer to instructions here – Lake Formation full table access for Amazon EMR on EC2 and Introducing runtime roles for Amazon EMR steps: Use IAM roles and AWS Lake Formation for access control with Amazon EMR. Fine Grained Access Control (FGAC) option is not supported for Spark on EMR with this feature since S3 location permission is full file path access.
First, we will get the setup ready with S3, sample database, table, and data. We will add a raw data set to S3 location, create a table with parquet data in another S3 location that represents the curated dataset for further downstream consumption. We will register the table data location with Lake Formation and grant permissions for the EMR run time role and Data-Analyst role.
Your S3 bucket will have the following structure.
Raw data – s3://<your-bucket-name>/raw/transactions/dt=2024-03-21/
Process data for table – s3://<your-bucket-name>/processed/transactions/
Spark script – s3://<your-bucket-name>/scripts/
Logs for the EMR cluster – s3://<your-bucket-name>/logs/
Step 1 – Create a parquet table in Data Catalog
From the Athena console query editor, create a table in Data Catalog.
-- Create a database
CREATE DATABASE finance_db;

-- Create an external table pointing to the S3 location
CREATE EXTERNAL TABLE IF NOT EXISTS finance_db.transactions_processed (
    transaction_id STRING,
    merchant_name STRING,
    amount DECIMAL(18,2),
    currency STRING,
    account_number STRING,
    card_type STRING,
    status STRING,
    region STRING
)
PARTITIONED BY (transaction_date DATE)
STORED AS PARQUET
LOCATION 's3:///processed/transactions/'
TBLPROPERTIES (
    'parquet.compress'='SNAPPY'
);
Step 2 – Register S3 location and grant table permission to IAM roles in Lake Formation
2.1 Register the table data location s3://<your-bucket-name>/processed/transactions/ with Lake Formation in Lake Formation mode using the custom S3 registration IAM role. For details on how to register locations with Lake Formation, refer Adding an Amazon S3 location to your data lake.
2.2 Grant DESCRIBE permission on the database finance_db and ALL permission on the table transactions_processed to your EMR runtime role.
2.3 Grant Data location permission to EMR runtime role on the curated table’s location. This is to allow writing to that location.
2.4 Grant DESCRIBE permission on the database finance_db and SELECT permission on the table transactions_processed to your Data-Analyst role. Exclude the columns transaction_id and account_number while granting SELECT permissions on the table to the Data-Analyst role.
3.2 Edit the S3 bucket name placeholder in the script (RAW_PATH and TABLE_PATH) to your resource names and upload to your S3 path s3://<your-bucket-name>/scripts/.
3.3 Make sure your EMR runtime role has access to the script location in its IAM policy permissions.
3.4 Submit and run the script as a step to the EMR cluster, following instructions at Add a Spark step.
What does the script do?
It populates raw records of transaction data into a Spark data frame, writes to the raw data bucket location using IAM permissions on the EMR runtime role. We apply some transformations and write directly to the S3 location of the table that is registered with Lake Formation, from the data frame using Spark’s native Parquet writer.
The following figure shows the stdout of the step.
The Java plugin integrated into EMR 7.13 automatically handles the access for the table’s data location registered with Lake Formation, so you don’t need to manually call the GetTemporaryDataLocationCredentials() API. In this example, the table data location s3://<your-bucket-name>/processed/transactions/ is registered with Lake Formation, for which EMR runtime role is granted ALL permissions. The direct S3 location access support by Lake Formation allows reading and writing to the location directly using Spark data frame.
Step 4 – Run query as Data-Analyst using Athena
Log in as the Data-Analyst role to the Athena console. Run a select query on the table as follows.
SELECT * FROM finance_db.transactions_processed WHERE status = 'DECLINED' AND transaction_date=DATE '2024-03-21';
The Data-Analyst role should see all but two columns of the table.
With these steps complete, we’ve read from and written to direct S3 locations using Spark data frames with the syntax s3://bucketname/prefix/, and accessed the same data using database_name.table_name syntax with Lake Formation permissions. This shows fine-grained access at table level and coarse-grained access at the file path level.
Clean up
To avoid incurring costs, clean up the resources you created for this post.
Delete the Data Catalog database and tables. This removes the related Lake Formation permissions too. Remove the S3 bucket registration from Lake Formation.
Delete the data files, logs, and the PySpark script of this post from your S3 bucket.
Terminate the EMR cluster.
Conclusion
In this post, we showed how to use Lake Formation’s direct S3 location access to read and write data files using Spark data frames from Amazon EMR, while maintaining unified governance through Lake Formation permissions. We walked through the GetTemporaryDataLocationCredentials() API and the AWS Lake Formation Credential Vending Plugin for AWS SDK v2 for Java, which is integrated into EMR release labels 7.13 and later.
This capability unifies permission management for both fine-grained table-based access and direct S3 file path access in Lake Formation. Your data scientists can now use spark.read.parquet() and spark.write alongside spark.sql(), governed by the same permissions, audited in the same CloudTrail logs, and managed from a single console.
To get started, launch an EMR 7.13 cluster and start exploring the feature. Here are some additional resources:
Acknowledgements: We would like to thank all the team members who worked to launch this feature successfully – Rajas Bhate, Akhil Yendluri, Kunal Parikh, Sharda Khubchandani, Dhananjay Badaya, Santhosh Padmanabhan, Nitin Agrawal and Sandeep Adwankar.
AWS DevOps Agent can investigate a growing range of production incidents autonomously. It diagnoses CrashLoopBackOff failures, traces ConfigMap deletions through audit logs, and correlates Amazon CloudWatch metrics with cluster events — all without human intervention.
But AWS DevOps Agent has a visibility boundary. When the data it needs lives outside its native integrations — on a node’s operating system, inside a third-party monitoring tool, behind a database’s internal diagnostics — the agent stalls. It can describe symptoms, but it can’t reach the evidence needed to identify root causes.
This post shows how to extend AWS DevOps Agent by building a custom Model Context Protocol (MCP) server that bridges that gap. Using a concrete example, we give AWS DevOps Agent structured access to Amazon EKS worker node diagnostics and explain how the same approach applies to data sources the agent can’t natively reach. By the end of this walkthrough, you will have a working MCP server that gives AWS DevOps Agent access to 20+ node-level log sources — providing autonomous investigation capabilities that can assist in root cause analysis compared to manual SSH sessions.
Prerequisites
Before you begin, make sure you have the following:
An Amazon EKS cluster with AWS Systems Manager Agent (SSM Agent) running on the worker nodes (included by default on Amazon EKS optimized AMIs)
Node.js v18 or later
AWS CLI v2
AWS CDK v2 installed and bootstrapped in your target account and Region
An AWS account with permissions to create IAM roles, Lambda functions, and Amazon S3 buckets
Familiarity with Amazon EKS, AWS Systems Manager, and the Model Context Protocol (MCP)
How AWS DevOps Agent discovers custom tools through MCP
MCP is an open standard that defines how AI agents discover and invoke external tools. AWS DevOps Agent supports connecting to custom MCP servers, which means you can expose new capabilities to it without modifying the agent itself. When you connect an MCP server to AWS DevOps Agent, the agent automatically discovers the available tools, understands their schemas, and calls them as part of its investigation workflow. You build and connect the MCP server — the agent handles the rest.
The extensibility model follows three steps: first, identify the data source that AWS DevOps Agent cannot natively access; second, build an MCP server that wraps safe, structured access to that data source; and third, connect the MCP server to AWS DevOps Agent so it can incorporate the new tools into its investigations.
Three design principles make this work. Return structured data, not raw text — pre-index findings with severity levels and stable IDs so the agent can filter, reference, and correlate them. Never give the agent a shell — mediate interactions through a controlled, auditable execution model. Make tools composable — design tool outputs to serve as inputs to other tools, creating a chain of evidence the agent can follow.
Why Amazon EKS node OS visibility matters
AWS DevOps Agent integrates with Amazon EKS to inspect pod status, read container logs, query CloudWatch Container Insights, and correlate cluster events. This covers application crashes, container-level resource exhaustion, and configuration drift.
However, EKS production issues with nodes originate in a layer these tools cannot reach: the node operating system. Artifacts such as iptables rules, full CNI configuration and IPAMD state, route tables, conntrack entries, dmesg kernel messages, containerd runtime logs, sysctl parameters, ENI metadata, and the unfiltered kubelet journal exist exclusively on the node. These artifacts are the primary evidence for diagnosing IP allocation failures, DNS resolution issues, network policy enforcement problems, storage mount timeouts, and node registration failures.
Integrating AWS DevOps Agent with an EKS node diagnostics MCP server
The sample-eks-node-diagnostics-mcp repository (sample-eks-node-diagnostics-mcp repository) demonstrates this pattern. It provides an MCP server that gives AWS DevOps Agent structured access to node-level diagnostic data, backed by AWS Systems Manager (SSM) Automation for safe, auditable execution.
How it works
Figure 1: End-to-end architecture of the EKS Node Diagnostics MCP server. AWS DevOps Agent discovers and invokes 19 tools through AgentCore Gateway, which dispatches SSM Automation runbooks to worker nodes for log collection and uploads results to Amazon S3 for extraction and indexing.
AWS DevOps Agent calls a collect tool with an instance ID.
The MCP server dispatches an SSM Automation execution to the target node, running the AWS-managed AWSSupport-CollectEKSInstanceLogs runbook.
The runbook collects 20+ log sources — kubelet, containerd, iptables, CNI config, route tables, dmesg, sysctl, ENI metadata, IPAMD logs, and more — packages them into an archive, and uploads it to an Amazon S3 bucket where you configure AWS KMS encryption.
A processing pipeline extracts the archive, pre-indexes errors with severity classification and stable finding IDs, and provides the results to you through additional MCP tools.
The server exposes tools for log collection, pre-indexed error retrieval, cross-file search and correlation, structured network diagnostics, and live packet capture. A typical agent workflow chains these together: collect → status → errors → search → correlate → read → summarize, with each step producing outputs that feed into the next.
AWS DevOps Agent does not get a shell on the node. Every interaction is mediated by SSM Automation — an auditable, IAM-controlled, non-interactive execution model.
Connecting through Amazon Bedrock AgentCore Gateway
The reference implementation uses Amazon Bedrock AgentCore Gateway to expose the Lambda-backed MCP server to AWS DevOps Agent. AgentCore Gateway converts Lambda functions into MCP-compatible tools and handles authentication, protocol translation, and tool discovery through a single managed endpoint.
The integration follows three steps:
Step 1: Create an OAuth authorizer with Amazon Cognito. The CDK stack provisions a Cognito User Pool configured for the OAuth 2.0 client credentials flow. This secures inbound access to the gateway — only clients with valid tokens can invoke tools.
Step 2: Create a gateway and register the Lambda as a target. Register the Lambda function that handles tool invocations as a target on the gateway. AgentCore Gateway automatically discovers the tool schemas from the Lambda and makes them available through the MCP protocol. The gateway endpoint becomes the single MCP URL for AWS DevOps Agent.
Step 3: Connect AWS DevOps Agent. Register the MCP server at the account level in the AWS DevOps Agent console, providing the gateway URL and OAuth configuration. Then allowlist the specific tools each Agent Space needs. AWS DevOps Agent authenticates by obtaining a JWT from the Cognito token endpoint using the client credentials grant and passes it as a Bearer token in requests to the gateway URL.
Deploying the MCP server
Deploy the entire stack using AWS CDK :
git clone https://github.com/aws-samples/sample-eks-node-diagnostics-mcp.git cd sample-eks-node-diagnostics-mcp chmod +x deploy.sh ./deploy.sh
The script walks you through cluster selection and node role configuration. Have the following ready before running the script: your target EKS cluster name, the IAM role ARN you attached to your worker nodes, and the AWS Region where your cluster runs. The script outputs your MCP gateway URL, OAuth credentials, and token endpoint — everything you need to configure the connection in AWS DevOps Agent. See the repository README for detailed deployment instructions, CI/CD mode, and prerequisite details.
Seeing it in action
To demonstrate the MCP server’s capabilities, we walk through a realistic node-level failure scenario on a test EKS cluster. We manually inject a fault that blocks pod DNS resolution at the iptables level — an issue that is invisible from kubectl since pods appear Running — then show how AWS DevOps Agent investigates and identifies the root cause using the MCP server’s tools.
Setting up the scenario
Start with an EKS cluster that has a managed node group with SSM Agent running (included by default on Amazon EKS optimized AMIs). Deploy a sample workload to one of the nodes:
Identify the node and instance ID where the pods are running:
kubectl get pods -n demo-app -o wide
Injecting the fault
WARNING: The following commands will disrupt DNS resolution for all pods on the target node. Only run these in a non-production test environment. Do not execute on production nodes.
Connect to the target node using SSM Session Manager and run the following commands to block pod DNS traffic at the iptables level. This simulates a subtle networking issue – pods continue running but can’t resolve DNS, and the root cause is only visible in the node’s iptables rules:
# Block pod traffic to kube-dns ClusterIP — pods run but DNS fails # Only affects FORWARD chain (pod traffic), not the node's own DNS sudo iptables -I FORWARD -d 10.100.0.10/32 -p udp --dport 53 -j DROP sudo iptables -I FORWARD -d 10.100.0.10/32 -p tcp --dport 53 -j DROP
Replace 10.100.0.10 with your cluster’s kube-dns ClusterIP (kubectl get svc kube-dns -n kube-system -o jsonpath=’{.spec.clusterIP}’).
This fault is particularly insidious because kubectl get pods shows all pods in Running state. The applications fail with DNS resolution errors, but there is no Kubernetes event or pod status that points to the cause. The iptables DROP rules targeting the kube-dns ClusterIP exist only in the node’s firewall configuration — a layer that no Kubernetes API call can inspect.
Investigating with AWS DevOps Agent
An engineer notices applications reporting DNS failures and asks AWS DevOps Agent to investigate:
“Pods on node i-xxxxxxxxxx in cluster EKS-sample (us-east-1) are running but applications report DNS resolution failures. Collect the node logs and investigate.”
Figure 2: Starting an investigation in AWS DevOps Agent. The engineer provides the symptom description and incident timestamp, and the agent autonomously plans and executes the investigation.
AWS DevOps Agent begins the investigation by recording the symptom and launching two parallel actions: collecting node logs via the nodelog_collect tool and checking cluster health. The cluster health check confirms all four nodes are running and SSM-online. The agent then polls the log collection status, tracking progress from 25% through 75% to completion. Once collection finishes, the agent fans out into parallel workstreams — running network diagnostics, performing quick triage, and collecting logs from a healthy node for comparison.
Figure 3: Investigation timeline showing the initial data collection phase. The agent identifies the symptom, confirms cluster health, collects node logs via SSM Automation, polls for completion, and launches parallel diagnostic workstreams.
With the initial data collected, the agent launches four parallel investigation tasks to maximize coverage and minimize time-to-root-cause: (1) deep-dive-iptables-routes examines the node’s firewall rules and routing table in detail, completing in 1 minute 44 seconds across 8 tool calls; (2) search-network-errors scans the collected logs for network-related error patterns, running 15 tool calls over 7 minutes 51 seconds; (3) collect-healthy-node gathers the same diagnostics from a known-good node for comparison, taking 13 tool calls over 4 minutes 55 seconds; (4) check-oom-and-pod-status investigates kernel OOM kills and pod health, executing 19 tool calls over 8 minutes 12 seconds. Each task produces a structured report that feeds into the final synthesis.
Figure 4: Parallel investigation phase. The agent runs four concurrent deep-dive tasks — iptables/route analysis, network error search, healthy node comparison, and OOM/pod status check — then synthesizes the findings into a unified report.
The iptables and route table deep-dive reveals the root cause. The agent identifies two CRITICAL findings: a FAULT-INJECT-DROP-POD-TO-POD rule in the FORWARD chain that drops inter-pod traffic, and a FAULT-INJECT-DROP-SERVICE-CIDR rule that drops forwarded traffic to the service CIDR range. It also flags a MEDIUM-severity finding — a blackhole route for 10.96.0.0/12 (the Kubernetes service CIDR) that does not exist on healthy nodes. The remaining checks come back normal: kube-proxy chains are intact, AWS VPC CNI SNAT/CONNMARK chains are properly configured, and the default gateway and ENI route tables are correct. This structured severity classification allows the agent to immediately focus on the critical items.
Figure 5: Deep-dive findings from the iptables and route table analysis. Two CRITICAL fault-injection DROP rules in the FORWARD chain are identified as the primary issue, while standard networking components — kube-proxy, VPC CNI, and routing — check normal.
The healthy node comparison confirms the diagnosis. The agent compares the unhealthy node against a known-good node across seven dimensions: security groups, ENI count, DNS configuration, iptables rules, route tables, conntrack entries, and IPAMD state. The key differences are definitive: the blackhole route for 10.96.0.0/12 exists only on the unhealthy node, kubelet API server timeout errors appear only on the unhealthy node, conntrack entries are 12x higher (1,962 vs 169), and IPAMD reconciliation errors are 5x more frequent. The iptables FORWARD chain counters show 2.4 billion packets processed on the unhealthy node versus zero on the freshly-started healthy node — confirming sustained traffic disruption.
Figure 6: Healthy node comparison confirming the diagnosis. The agent compares diagnostics across both nodes and identifies five key differences — the blackhole route, elevated conntrack entries, and high FORWARD chain packet counts exist only on the affected node.
The agent synthesizes the findings into a definitive root cause determination. It identifies a fault-injection namespace on the EKS cluster that is running chaos experiments, introducing three specific network-disrupting modifications on the target node: (1) a FAULT-INJECT-DROP-POD-TO-POD iptables rule in the FORWARD chain that drops inter-pod traffic, (2) a FAULT-INJECT-DROP-SERVICE-CIDR rule that drops forwarded traffic to the Kubernetes service CIDR, and (3) a blackhole route for 10.96.0.0/12 that does not exist on healthy nodes. Together, these three modifications create a multi-vector network disruption — pods appear Running but cannot communicate with each other or reach Kubernetes services, including kube-dns.
Figure 7: Root cause determination. The agent traces the multi-vector network disruption to three fault-injection modifications — two iptables DROP rules and a blackhole route — deployed by a chaos experiment namespace on the target node.
Cleaning up the fault
To restore the node after the demo, connect via SSM Session Manager and run:
The EKS node diagnostics use case demonstrates the pattern, but the architecture generalizes to systems where the SSM Agent is running and you can define an SSM Automation runbook to collect the data you need.
For example, an EC2 instance with SSM Agent can use this same approach — collect OS-level logs, network configuration, package state, or application diagnostics through a custom or pre-built SSM Automation runbook, upload results to S3, and expose them through MCP tools. The same applies to ECS container instances (Docker daemon logs, ECS agent state, iptables), on-premises servers registered via SSM Hybrid Activations, or managed nodes in your fleet.
The pattern also extends beyond SSM-managed hosts. Network devices can be reached through API calls to their management planes, databases through read-only diagnostic queries, and third-party APM tools through vendor API integrations. In each case, the same three-step approach holds: identify the unreachable data, build an MCP server that wraps safe access to it, and connect it to AWS DevOps Agent.
When to use this approach This pattern works well for incident response where diagnostic data lives outside AWS DevOps Agent’s native reach, fleet-wide triage where manual access to individual systems is impractical, and cross-source correlation where evidence spans multiple log sources.
It is not a replacement for continuous monitoring (use CloudWatch Container Insights or Prometheus for real-time alerting), log shipping (if you have compliance requirements for continuous retention), or native integrations where the agent already has access to the data source.
The reference implementation requires SSM Agent running on the nodes with appropriate IAM permissions. It is a proof of concept — validate it in non-production environments before using it with production workloads.
Clean up
Cost considerations: This solution uses AWS Lambda, Amazon S3, AWS KMS, Amazon Cognito, and Amazon Bedrock AgentCore Gateway. Costs vary based on usage. Lambda charges apply per invocation and duration. S3 charges apply for log storage. KMS charges a per-key monthly fee plus per-request charges. Cognito charges per monthly active user. AgentCore Gateway pricing is based on API calls. For current pricing details, see the AWS Pricing page for each service. To minimize costs during evaluation, delete the stack when not in use.
Remove the deployed resources by running cdk destroy from the repository root. The S3 log bucket uses a RETAIN removal policy — delete it manually after stack destruction if needed.
Conclusion
MCP provides a standardized extensibility mechanism that lets you bridge visibility gaps in AWS DevOps Agent without modifying the agent itself. The pattern is straightforward: identify the unreachable data source, build an MCP server that wraps safe and structured access to it, and connect it to AWS DevOps Agent through Amazon Bedrock AgentCore Gateway. The agent handles the reasoning. The MCP server handles the data access.
To get started:
Deploy the reference implementation (sample-eks-node-diagnostics-mcp repository) in a non-production environment.
Review the MCP specification (MCP specification).
Explore the Amazon EKS troubleshooting documentation (Amazon EKS troubleshooting documentation).
Connect custom MCP servers to AWS DevOps Agent — see the Connecting MCP Servers guide in the AWS DevOps Agent documentation.
Set up AgentCore Gateway — see the Amazon Bedrock AgentCore Gateway quick start guide.
In this post, we explore how to build an online shopping AI agent. We focus on its architecture and implementation with Amazon OpenSearch Service, Amazon Bedrock AgentCore, and Strands Agents. Amazon Bedrock AgentCore is an agentic platform for deploying and operating those agents and tools securely at scale without managing infrastructure. AgentCore Runtime is the secure, serverless runtime that hosts your Strands Agents and tools as containerized applications. Strands Agents is an open source SDK for building AI agents. In this SDK, an agent is defined by a model, tools, and a prompt. Tools are callable functions that allow agents to perform actions beyond text generation, such as API calls, database queries, and file operations. The framework lets the model autonomously plan steps and invoke tools to complete tasks.
Today’s AI shopping assistants understand natural language, context, and shopping intent, creating a more human-like interaction. These assistants handle complex shopping requirements, such as “Find me a formal dress under $200 that’s appropriate for a summer wedding.” They maintain conversation history, process follow-up questions naturally, and provide personalized recommendations based on user preferences and past interactions. Customers can use visual search to upload images of items that they want, and the AI finds similar products across multiple retailers, matching styles and patterns. The goal is to provide instant, relevant, and personalized assistance at scale, creating a more efficient shopping journey for consumers worldwide.
AI agents combined with Retrieval Augmented Generation (RAG) on Amazon OpenSearch Service represent an evolution in conversational search. This integration builds AI agents on enriched catalogs, supporting context-aware and autonomous search experiences while maintaining accuracy and relevance through grounded responses.
Solution overview
The following diagram illustrates the solution architecture of an AI-powered online shopping agent built using Strands Agents, Amazon Bedrock AgentCore Runtime, and Amazon OpenSearch Service. For simplicity, the diagram doesn’t show authentication and authorization. In a production setup, secure access to the backend by using mechanisms such as Amazon API Gateway, AWS Identity and Access Management (IAM) roles, or OAuth-based authentication.
The following is a walkthrough of the reference architecture:
The user submits a question through the front-end application. AgentCore Runtime receives the request and routes it to the Strands Retail Agent.
The Strands Agent processes the task and invokes the search_product_catalog tool.
OpenSearch Service performs semantic search and returns relevant product results.
The Strands Agent invokes Amazon Bedrock large language models (LLMs) to generate a natural language response.
The agent response is returned to the user through the front end.
Walkthrough
The following section walks you through how to build an online shopping AI agent.
Prerequisites
To implement this solution, you need an AWS account. You also need an OpenSearch Service domain with OpenSearch version 2.13 or later. You can use an existing domain or create a new domain.
To use the vector search capabilities of OpenSearch Service with Strands Agents on AgentCore, you use ingest pipelines. These ingestion pipelines apply built-in processors to pre-process your documents before you index them in OpenSearch Service.
You use the text_embedding processor, which relies on the ML Commons plugin and a registered embedding model—Amazon Nova Multimodal Embeddings on Amazon Bedrock. OpenSearch Service uses the ML Commons plugin to generate vector embedding for your data and uses the same model to convert incoming queries into vectors. This supports semantic search across your indexed content.
You extend your semantic search backend by adding an agent built with Strands Agents and deployed on Amazon Bedrock AgentCore.
Code samples provided in this post are tested in Python 3.11. You only need to install Python 3.11 in your environment to execute the python scripts. You also need Node.js 18 or later installed to use the AgentCore CLI. The provided code scripts will deploy into your AWS account so make sure your terminal has access to necessary AWS credentials.
Install AgentCore CLI
Install the AgentCore CLI globally using npm:
npm install -g @aws/agentcore
Python Dependencies
You also need to create a requirements.txt file with following dependencies in your workspace to deploy the agents.
Run pip install -r requirements.txt in your terminal to install the required dependencies. To avoid conflicts with other dependencies in your system, you can use a virtual environment.
Now, walk through each step.
Step 1: Configure IAM permissions
Complete the following steps to register the Nova Multimodal Embeddings model with OpenSearch Service and verify that your OpenSearch Service domain has permission to invoke the Amazon Bedrock API.
Go to the IAM console and create a new role with a custom trust policy. Add the following trust policy.
Give your role a name and create it. For this post, we use OpenSearchBedrockEmbeddingRole as the role name. OpenSearch Service uses this role to invoke the Nova Multimodal Embeddings model on Amazon Bedrock.
On the Permissions tab, attach an inline policy with the following permissions. For this post, we name this policy OpenSearchBedrockEmbeddingPolicy.
Create a passRole policy with the following JSON document and assign it to the IAM role that creates the ML connector. This lets the principal running the Python code pass the OpenSearchBedrockEmbeddingRole to OpenSearch. Replace <your-aws-account-id> with your own AWS account ID.
By using fine-grained access control (FGAC), map the IAM role as a backend role for the ml_full_access role in the OpenSearch Dashboards Security plugin. This mapping lets the user create ML connectors:
Log in to OpenSearch Dashboards and open the Security page from the navigation menu.
Choose Roles and select ml_full_access.
Choose Mapped Users and Manage Mapping.
Under Backend roles, add the ARN of the IAM role that you created in the previous steps.
Step 2: Connect to the model by using OpenSearch ML Connectors
In this section, you create an ML connector to link OpenSearch Service with the Bedrock Nova Multimodal Embeddings model. You then register and deploy the model so you can use it for neural search queries.
Create a file named create-connector.py with the following code. Replace <your hostname>, <your region>, and <your account id> placeholders within the code.
Run python create-connector.py in your terminal by using the IAM role with ml_full_access and passRole permissions created in the previous step. This script creates a connector between OpenSearch Service and the Bedrock Nova Multimodal Embeddings model.
The program responds with connector_id. Take a note of it. Then, navigate to OpenSearch Dashboards and open Dev Tools. Create a model group against which to register this model in the OpenSearch Service domain.
POST /_plugins/_ml/model_groups/_register
{
  "name": "agent-conversational-search-model-group",
  "description": "A model group for bedrock Nova embedding models used for conversational search"
}
Register a model by using connector_id and model_group_id.
Run the following API call to deploy the model. Use the registered model ID from the previous step.
POST /_plugins/_ml/models/<registered-model-id>/_deploy
Step 3: Create an ingest pipeline for data indexing
Use the following code to create an ingest pipeline for data indexing. The pipeline establishes a connection to the embedding model, retrieves the embedding for the title field, and stores it in the OpenSearch index.
PUT /_ingest/pipeline/nova_multimodal_embedding
{
  "description": "Text embedding pipeline using nova_multimodal_embedding",
  "processors": [
    {
      "text_embedding": {
        "model_id": "<deployed model id>",
        "field_map": {
          "title": "title_vector"
        }
      }
    }
  ]
}
Step 4: Create an index for storing data
Create an index named product for storing data by using Dev Tools. This index stores raw text and 1024-dimensional embeddings of the title field, and uses the ingest pipeline you created in the previous step.
Use the following code to ingest the sample product data in Dev Tools.
POST /_bulk
{"index": {"_index": "product", "_id": "2"}}
{"id":2,"title":"Mens Casual Premium Slim Fit T-Shirts","price":22.3,"description":"Slim-fitting style, contrast raglan long sleeve, three-button henley placket, light weight & soft fabric for breathable and comfortable wearing.","category":"men's clothing","image":"https://fakestoreapi.com/img/71-3HjGNDUL._AC_SY879._SX._UX._SY._UY_.jpg","rating":{"rate":4.1,"count":259}}
{"index": {"_index": "product", "_id": "3"}}
{"id":3,"title":"Mens Cotton Jacket","price":55.99,"description":"great outerwear jackets for Spring/Autumn/Winter, suitable for many occasions, such as working, hiking, camping, mountain/rock climbing, cycling, traveling or other outdoors.","category":"men's clothing","image":"https://fakestoreapi.com/img/71li-ujtlUL._AC_UX679_.jpg","rating":{"rate":4.7,"count":500}}
{"index": {"_index": "product", "_id": "4"}}
{"id":4,"title":"Mens Casual Slim Fit","price":15.99,"description":"The color could be slightly different between on the screen and in practice.","category":"men's clothing","image":"https://fakestoreapi.com/img/71YXzeOuslL._AC_UY879_.jpg","rating":{"rate":2.1,"count":430}}
{"index": {"_index": "product", "_id": "5"}}
{"id":5,"title":"John Hardy Women's Legends Naga Gold & Silver Dragon Station Chain Bracelet","price":695,"description":"From our Legends Collection, the Naga was inspired by the mythical water dragon that protects the ocean's pearl.","category":"jewelery","image":"https://fakestoreapi.com/img/71pWzhdJNwL._AC_UL640_QL65_ML3_.jpg","rating":{"rate":4.6,"count":400}}
Step 6: Query the index
Run the following API call to test semantic search by using the Nova Multimodal Embeddings model.
Import the Runtime app with from bedrock_agentcore.runtime import BedrockAgentCoreApp.
Initialize the app in your code with app = BedrockAgentCoreApp().
Create the OpenSearch Service connection and search query with the @tool decorator.
Decorate the invocation function with the @app.entrypoint decorator.
Let AgentCore Runtime control the running of the agent with app.run().
Now, complete the following steps:
Make sure that you have installed the necessary dependencies from the Prerequisites section of this post.
Create and save a file named search_agent.py with the following code. Replace <your hostname>, <your region>, and <your account id> placeholders within the code.
from strands import Agent, tool
import argparse
import json
from bedrock_agentcore.runtime import BedrockAgentCoreApp
from strands.models import BedrockModel
import boto3
from opensearchpy import OpenSearch, RequestsHttpConnection
from requests_aws4auth import AWS4Auth
app = BedrockAgentCoreApp()
@tool
def search_products(query: str, size: int = 5):
try:
# OpenSearch configuration
host = '' ## CHANGE THIS, DOMAIN ENDPOINT WITHOUT HTTPS!
region = '' ##CHANGE THIS
model_id= '' ##CHANGE THIS with your deployed model id in OpenSearch
service = 'es'
credentials = boto3.Session().get_credentials()
awsauth = AWS4Auth(credentials.access_key, credentials.secret_key, region, service, session_token=credentials.token)
# Create OpenSearch client
client = OpenSearch(
hosts=[{'host': host, 'port': 443}],
http_auth=awsauth,
use_ssl=True,
verify_certs=True,
connection_class=RequestsHttpConnection
)
"""Search products in OpenSearch using neural search"""
search_body = {
"_source": False,
"fields": ["title", "price", "category", "image"],
"size": size,
"query": {
"neural": {
"title_vector": {
"query_text": query,
"model_id": model_id,
"k": 3
}
}
}
}
response = client.search(
body=search_body,
index="product"
)
products = []
for hit in response['hits']['hits']:
fields = hit.get('fields', {})
product = {
'title': fields.get('title', [''])[0] if fields.get('title') else '',
'price': fields.get('price', [''])[0] if fields.get('price') else '',
'category': fields.get('category', [''])[0] if fields.get('category') else '',
'image': fields.get('image', [''])[0] if fields.get('image') else ''
}
products.append(product)
return f"Found {len(products)} products: {json.dumps(products, indent=2)}"
except Exception as e:
return f"Search error: {str(e)}"
model_id = "global.anthropic.claude-haiku-4-5-20251001-v1:0"
model = BedrockModel(
model_id=model_id,
)
agent = Agent(
model=model,
tools=[search_products],
system_prompt="You're a helpful assistant. You can do product search, and tell the product details."
)
@app.entrypoint
def strands_agent_bedrock(payload):
"""
Invoke the agent with a payload
"""
user_input = payload.get("prompt")
print("User input:", user_input)
response = agent(user_input)
return response.message['content'][0]['text']
if __name__ == "__main__":
#strands_agent_bedrock({"prompt": "Search jacket"}) ##UNCOMMENT THIS FOR TESTING
#app.run() ##UNCOMMENT THIS FOR DEPLOYMENT, MAKE SURE THE ABOVE LINE IS COMMENTED WHEN YOU ARE DEPLOYING TO AGENTCORE
This deploys your agent locally for testing purposes.
Navigate to the IAM console and add the AmazonBedrockLimitedAccess permission policy to the principal running the code.
Navigate to OpenSearch Dashboards and, from the left menu, choose Security plugin, then choose Roles.
Choose Create Role.
Name the role agentcore-permissions.
Under cluster permissions, add cluster:admin/opensearch/ml/models/get and cluster:admin/opensearch/ml/predict.
Under index permissions, enter product* as the index pattern. Add search and get permissions.
Create the role.
Choose the role you created, switch to the Mapped Users tab, choose Manage mapping, and add the role that you use for running the Python code as a backend role.
Uncomment the line strands_agent_bedrock({"prompt": "Search jacket"}) and make sure the app.run() line is commented in the code.
Run python search_agent.py in your terminal to start the shopping agent. The output should look similar to the following.
"Here are the jacket search results:\n\n1. **Mens Cotton Jacket** - $55.99\n2. **Mens Casual Slim Fit** - $15.99\n3. **Mens Casual Premium Slim Fit T-Shirts** - $22.30\n4. **John Hardy Women's Legends Naga Gold & Silver Dragon Station Chain Bracelet** - $695.00\n\nThe most relevant jacket option is the **Mens Cotton Jacket** at $55.99. Would you like to know more about any of these products?
Comment strands_agent_bedrock({"prompt": "Search jacket"}) and uncomment the app.run() line in the code before going into the next step.
Step 8: Configure and launch your agent to Bedrock AgentCore Runtime
The AgentCore CLI is a command-line tool provided by AWS that simplifies deployment of agents to Amazon Bedrock AgentCore Runtime. When you run the CLI deployment command, it automates the entire deployment workflow: it creates the necessary IAM execution role with proper permissions, packages your Python application code along with its dependencies, uses AWS CodeBuild to build an optimized Docker container image, pushes that container image to Amazon Elastic Container Registry (ECR), and finally provisions the AgentCore Runtime environment that hosts your containerized agent. This eliminates the need for manual Dockerfile creation, container builds, or infrastructure management.
Before you start this step, make sure you have gone through section 7 and installed the AgentCore CLI and Python dependencies listed in the Prerequisites section.
Create a policy named AgentCoreAccessPolicy with the following permissions and attach it to the role running the code. Replace <ACCOUNT_ID> and <REGION> placeholders.
Create a file named agentcore.yaml in your project directory with the following configuration. Replace <REGION>, <ACCOUNT_ID>, and <OPENSEARCH_DOMAIN_NAME> placeholders:
Map your AgentCore execution role to an OpenSearch backend role so the agent can access your data.
Navigate to OpenSearch Dashboards. From the left menu, choose the Security plugin, then choose Roles.
Search for agentcore-permissions and choose the role. Then, navigate to the Mapped Users tab, choose Manage mapping, and add arn:aws:iam::<ACCOUNT_ID>:role/AmazonBedrockAgentCoreSDKRuntime-us-east-1-custom as a backend role. Replace the <ACCOUNT_ID> placeholder with your account ID.
Step 10: Invoke the Bedrock AgentCore Runtime
You can test the agent in Agent Sandbox. Enter the prompt Search jacket less than 50$, and the agent returns the relevant result from the OpenSearch Service index with a summary.
In real-world scenarios, you can design a search application with a Strands Agent deployed in AgentCore Runtime. You can add AgentCore Memory, which gives your AI agents the ability to remember past interactions and provide more context-aware, personalized conversations.
Cleanup
To avoid incurring future charges, delete the resources created while building this solution:
In this post, you saw how to create a conversational search with Amazon OpenSearch Service and Strands Agents. You also learned how to deploy the agent on Amazon Bedrock AgentCore Runtime. You can further enhance this shopping agent by using other AgentCore capabilities. For example, AgentCore Memory retains user preferences and past interactions across sessions, AgentCore Identity manages shopper authentication and access control, and AgentCore Observability helps you monitor and debug agent behavior in production. Together, these services help you build shopping experiences that deliver instant, relevant assistance at scale.
Now it’s your turn. Build your own conversational search experience by integrating OpenSearch Service and Strands Agents with your product catalog. To learn more, see the Amazon OpenSearch Service and Amazon Bedrock AgentCore detail pages.
Whether you’re processing financial data, managing e-commerce orders, or training machine learning (ML) models, efficiently coordinating complex processes is essential. Amazon Web Services (AWS) offers two services for workflow orchestration: Amazon Managed Workflows for Apache Airflow (Amazon MWAA) and AWS Step Functions.
This post explores how to select the right workflow orchestration service based on your specific use case requirements. We’ll examine key workflow characteristics, present real-world scenarios, and provide practical guidance to help you make an informed decision for your particular needs.
Understanding workflow orchestration requirements
Before exploring specific services, consider the key dimensions that influence workflow orchestration needs:
Data statefulness: Does your workflow process independent units of work (stateless) or create dependencies where each step modifies data from previous steps (stateful)?
Execution duration: Are your workflows short-lived (seconds to minutes) or long-running (hours to days)?
Scheduling requirements: Do you need built-in time-based execution or rely primarily on event triggers?
Recovery capabilities: How critical is the ability to restart from specific failure points rather than reprocessing entirely?
Integration complexity: What systems, services, and data sources need to be coordinated?
Security and access control: Do you need fine-grained permissions for different workflow components?
Let’s explore how these requirements map to real-world use cases and the appropriate orchestration solutions.
Use case: Enterprise data analytics pipeline
This scenario illustrates how Amazon MWAA handles complex, stateful data pipelines with built-in scheduling and granular recovery.
Business challenge
A global financial services company processes massive volumes of transaction data daily, requiring sophisticated data analytics capabilities. Their requirements include:
Designed to process 5-10 TB of financial transaction data daily
Running complex extract, transform, and load (ETL) jobs with multiple transformation stages
Generating regulatory reports for compliance use cases
Supporting both scheduled batch processing and event-driven workflows
Capable of handling long-running jobs that can take up to 12 hours
Ensuring data consistency and integrity throughout the pipeline
Workflow characteristics
Data statefulness: Highly stateful workflows where each processing step modifies transaction data, creating dependencies throughout the pipeline
Scheduling needs: Mixed time-based and event-driven patterns
Recovery requirements: Critical ability to resume from specific failure points
Integration complexity: Orchestrates multiple AWS services and external systems
Solution: Amazon Managed Workflows for Apache Airflow (Amazon MWAA)
For this enterprise data analytics scenario, Amazon MWAA provides capabilities that align well with these requirements:
Stateful workflow management
MWAA excels at managing complex, stateful data pipelines where data consistency is critical. When processing terabytes of financial data, MWAA’s ability to resume from the last successful checkpoint helps prevent costly reprocessing and maintain data integrity.
The following code example demonstrates how to structure a complex financial ETL pipeline in MWAA:
# Example: Complex ETL pipeline with proper dependency management
from airflow import DAG
from airflow.operators.python_operator import PythonOperator
from datetime import datetime, timedelta

dag = DAG(
	'financial_etl_pipeline',
	schedule_interval='0 2 * * *',  # Daily at 2 AM
	start_date=datetime(2024, 1, 1),
	catchup=False
)

# Define tasks
extract_transactions = PythonOperator(task_id='extract_transactions', ...)
extract_market_data = PythonOperator(task_id='extract_market_data', ...)
transform_data = PythonOperator(task_id='transform_data', ...)
load_warehouse = PythonOperator(task_id='load_warehouse', ...)
generate_reports = PythonOperator(task_id='generate_reports', ...)

# Express complex dependencies clearly
[extract_transactions, extract_market_data] >> transform_data >> [load_warehouse, generate_reports]
This Directed Acyclic Graph (DAG) shows how to define task dependencies for parallel data extraction followed by sequential transformation and loading operations. The >> operator clearly defines the workflow dependencies. Transformation only begins after both extraction tasks complete successfully.
Built-in scheduling capabilities
MWAA includes native scheduling capabilities, making it straightforward to set up recurring workflows without additional services. The schedule_interval parameter in the DAG definition provides flexible scheduling options using cron syntax.
Granular recovery and resume control
During production incidents, operations teams can use the MWAA web interface to restart or bypass specific steps with a few clicks. This capability is important for stateful applications where restarting the entire workflow could compromise data consistency.
The MWAA web interface provides a visual representation of the workflow execution, allowing operators to:
Identify failed tasks – Examine task logs for troubleshooting – Clear the status of specific tasks – Restart execution from specific points
Figure 1: A Directed Acyclic Graph (DAG) in MWAA showing parallel execution ofAmazon Redshift Data APItasks. If any task fails, you can re-run specific tasks rather than restarting from the beginning.
Infrastructure planning: While MWAA requires capacity planning, the automatic scaling capabilities effectively handle variable workloads by setting minimum and maximum worker counts.
Security model: MWAA uses a shared execution role across DAGs, but you can implement additional security through resource-level policies and separate environments for different teams.
Cost predictability: The worker-hour pricing model provides predictable costs for long-running jobs, making budget planning more straightforward.
Use case: Real-time serverless application orchestration
This scenario shows how AWS Step Functions handles event-driven, serverless workflows that need to scale automatically with unpredictable traffic.
Business challenge
An e-commerce platform needs to orchestrate real-time order processing workflows that can handle thousands of concurrent orders during peak shopping periods. Their requirements include:
Designed for processing customer orders in real-time (targeting sub-second response times)
Coordinating payment validation, inventory checks, and fulfillment
For this real-time e-commerce scenario, AWS Step Functions provides capabilities that align well with these requirements:
Serverless architecture and automatic scaling
Step Functions automatically scales to handle traffic spikes without infrastructure management. During peak shopping events like Black Friday, the service handles increased load without manual intervention.
Event-driven workflow execution
Step Functions is designed for order-triggered workflows that need immediate execution. The following JSON definition shows how to structure an e-commerce order processing workflow:
This Step Functions definition demonstrates several key capabilities: – The ValidatePayment state includes built-in retry logic with exponential backoff – The CheckInventory state uses parallel execution to simultaneously check multiple warehouses – Each Lambda function is called via its Amazon Resource Name (ARN), providing direct integration with AWS services
Figure 2: A complex workflow in AWS Step Functions, involving multiple stages of data processing. The parallel execution doesn’t allow resuming from a specific mid-execution step, but the branching structure provides automated error handling and recovery.
Native AWS service integration
Step Functions provides direct integration with Lambda functions, SQS queues, SNS topics, and DynamoDB, eliminating the need for custom connectors or additional infrastructure components.
Cost-effective pay-per-use model
The pay-per-execution pricing model aligns with variable order volumes, keeping costs minimal during slow periods while scaling automatically during busy times.
Human approval workflow support
Step Functions supports human approval steps, making it suitable for high-value order workflows that require manual review or approval processes.
Implementation considerations
Error handling: Built-in retry mechanisms and error handling patterns help provide reliable order processing with configurable retry policies.
Visual monitoring: The Step Functions console provides real-time visibility into order processing status, enabling quick identification of bottlenecks.
Security model: Fine-grained AWS Identity and Access Management (IAM) roles per step so that payment processing functions have different permissions than inventory management functions.
Choosing the right workflow orchestration service
When selecting between Amazon MWAA and AWS Step Functions, consider these workflow characteristics:
Consider Amazon MWAA when your use case involves:
Complex stateful data processing where workflows modify data state and require recovery mechanisms to maintain consistency
Long-running batch jobs executing for hours or days where computational investment is substantial
Built-in scheduling requirements where regular batch processing needs time-based orchestration
Granular recovery needs where resuming from specific failure points is business-critical
Complex task dependencies involving sophisticated relationships between workflow tasks
Existing Apache Airflow expertise where teams have substantial investment in Apache Airflow knowledge
Consider AWS Step Functions when your use case involves:
Event-driven serverless workflows triggered by external events requiring immediate response
Stateless processing where each workflow execution operates independently
Short to medium duration tasks completing within minutes to hours
Heavy AWS service integration involving extensive coordination with Lambda functions and other AWS services
Human approval workflows requiring manual intervention or decision-making
Variable load patterns with unpredictable traffic requiring automatic scaling
Decision framework
To help guide your decision process, consider the following questions:
Figure 3: Decision tree guiding through key considerations for choosing between Amazon MWAA and AWS Step Functions based on workflow characteristics.
Figure 4: Comprehensive comparison between Amazon MWAA and AWS Step Functions, highlighting decision factors for choosing the right workflow orchestration service.
Conclusion
Both Amazon Managed Workflows for Apache Airflow and AWS Step Functions are workflow orchestration services, each designed to address specific use case requirements. By understanding your workflow characteristics and aligning them with the strengths of each service, you can make an informed decision that supports your business needs.
For complex, stateful workflows with long execution times and sophisticated recovery requirements, Amazon MWAA provides robust capabilities. For event-driven, serverless workflows with tight AWS integration and variable load patterns, AWS Step Functions is a strong fit.
Remember that these services are not mutually exclusive. Many organizations use both to address different workflow orchestration needs across their application portfolio. By focusing on your specific use case requirements, you can select the right tool for each job and build resilient, efficient workflow orchestration solutions on AWS.
If you have questions or feedback about choosing between these services, leave a comment.
Enterprises running transactional workloads on Amazon Aurora PostgreSQL-Compatible Edition (Aurora PostgreSQL) need their operational data available for analytics. However, analytical queries and cross-database joins compete for resources on OLTP-optimized clusters. Batch exports introduce latency, and when data spans multiple Aurora clusters, there’s no straightforward way to join datasets or run cross-domain analytics. Real-time change data capture (CDC) addresses this by streaming row-level changes into a separate analytics layer. However, most CDC approaches write append-only records that require downstream consumers to reconstruct current state from the change log.
In this post, we show you how to build a CDC pipeline that delivers query-ready Iceberg tables directly. The pipeline captures inserts, updates, and deletes from Aurora PostgreSQL and applies them as row-level operations in Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3). The destination tables always reflect the current state of the source database. You use Debezium on Amazon MSK Connect for change capture and Amazon Managed Streaming for Apache Kafka (Amazon MSK) for streaming. You also use AWS Lambda to transform CDC events and resolve operation semantics, and Amazon Data Firehose to deliver records into Iceberg tables. You deploy the infrastructure using the AWS Cloud Development Kit (AWS CDK).
The following diagram shows the architecture of the CDC pipeline.
Figure 1. CDC pipeline architecture from Aurora PostgreSQL to Amazon S3 Tables.
The pipeline uses six components:
Aurora PostgreSQL to Debezium. Debezium runs on MSK Connect in your VPC and uses PostgreSQL’s native logical replication to stream row-level changes from the write-ahead log (WAL), with minimal impact on query performance.
Debezium to Amazon MSK. The ByLogicalTableRouterSMT reroutes CDC events from multiple tables into a single topic (aurora.cdc.all-tables), retaining the source table name in each message.
Amazon MSK to Firehose. Firehose connects to the MSK cluster using the IAM access control over AWS PrivateLink and continuously polls the topic for new messages.
Firehose to Lambda. For each batch, Firehose invokes the Lambda function to decode the Kafka message, flatten the Debezium envelope, and set otfMetadata routing with the destination table and operation type.
Firehose to S3 Tables. Firehose reads the otfMetadata, routes each record to the correct Iceberg table, and performs the appropriate row-level operation using configured unique keys (for example, order_id for orders). S3 Tables handles compaction and snapshot management automatically.
Firehose supports one MSK topic per delivery stream. The single-topic routing pattern uses a Debezium SMT to consolidate multiple tables into one topic, and a Lambda function to route records to the correct destination. With this, you can serve multiple tables through one Firehose stream, reducing cost and operational complexity.
Debezium event transformation
Debezium produces CDC events in an envelope structure containing both the previous and current state of a row, along with metadata about the source database, table, and operation type. However, Firehose expects records in a flattened JSON format with routing metadata that indicates the target table and operation type.
The Lambda function bridges this gap by performing three operations on each record:
Decode. When Firehose uses Amazon MSK as a source, it delivers the Kafka message value as a base64-encoded string in the kafkaRecordValue field. The function base64-decodes this field to obtain the raw Debezium JSON payload.
Flatten and extract. Pulls the row data from the Debezium envelope. For inserts and updates, the function uses the after field (the row after the change). For deletes, it uses the before field, because the after field is null when a row is removed.
Route. Sets the otfMetadata block with destinationTableName (extracted from the Debezium source.table field) and operation (mapped from Debezium’s single-character codes to Firehose’s operation types).
The following table shows how Debezium operation codes map to Firehose Iceberg operations:
Debezium code
Meaning
Firehose operation
c
Row created (insert)
insert
u
Row updated
update
d
Row deleted
delete
r
Snapshot read (initial load)
insert
When Debezium starts with snapshot.mode=initial, it reads all existing rows and emits them as r (read) events. These represent rows that existed before CDC began, so they are mapped to insert to establish the baseline state in the destination tables.
For example, the function transforms this Debezium envelope:
The kafkaRecordValue contains the base64-encoded flattened row data (for example, {"order_id": 1, "customer_id": 1, "total_amount": 299.99}), and the otfMetadata block tells Firehose which table to write to and which operation to perform.
PostgreSQL supports change data capture through its logical replication framework, which allows database changes to be streamed from the write-ahead log (WAL). Debezium uses this mechanism to continuously read row-level changes and publish them to Kafka topics.
Create a publication that defines which tables are included in the change stream. Debezium automatically creates the logical replication slot when the connector starts for the first time, so you don’t need to create one manually.
CREATE PUBLICATION dbz_publication FOR TABLE public.orders, public.products;
Verify the publication was created:
SELECT * FROM pg_publication WHERE pubname = 'dbz_publication';
You should see one row returned, confirming the publication is active.
Important: When the Debezium connector starts (Step 6), it creates a replication slot named debezium_slot. This slot retains WAL segments until consumed. If the connector is stopped for an extended period, WAL segments can accumulate and increase storage usage on the Aurora cluster. Monitor the ReplicationSlotDiskUsageAmazon CloudWatch metric for your Aurora cluster.
Step 2: Build and register the Debezium plugin
MSK Connect runs connectors using custom plugins that you upload to Amazon S3. In this step, you download the Debezium PostgreSQL connector, package it as a ZIP file, upload it to S3, and register it with MSK Connect.
First, create an S3 bucket for the plugin, or use an existing metadata management bucket:
Note the customPluginArn and workerConfigurationArn from the output. You need these for the CDK configuration in the next step.
Note: The custom plugin and worker configuration are created through the AWS CLI because the Debezium connector JARs must be downloaded from the Debezium project and packaged manually. The remaining infrastructure is deployed using the AWS CDK in the following steps.
Step 3: Configure the CDK project
Clone the sample repository and install dependencies:
git clone https://github.com/aws-samples/sample-aurora-cdc-s3tables.git
cd sample-aurora-cdc-s3tables/cdk
npm install
Open cdk/lib/v2/config.ts and update the configuration values to match your environment:
export const CONFIG = {
account: '<your-account-id>',
region: '<your-region>',
// VPC - must match your Aurora cluster's VPC
vpcId: '<your-vpc-id>',
subnetIds: ['<subnet-1>', '<subnet-2>'],
auroraSecurityGroupId: '<aurora-security-group-id>',
// Aurora connection details
auroraEndpoint: '<aurora-cluster-endpoint>',
auroraPort: '5432',
auroraDbName: '<database-name>',
auroraUser: '<db-user>',
auroraSecretArn: '<secrets-manager-arn>',
// Debezium - use the ARNs from Step 2
debeziumPluginArn: '<customPluginArn-from-step-2>',
debeziumWorkerConfigArn: '<workerConfigurationArn-from-step-2>',
debeziumPluginBucket: '<your-plugin-bucket-name>',
debeziumTopicPrefix: 'aurora.cdc',
debeziumTables: 'public.orders,public.products',
// S3 Tables - the table bucket name must be globally unique
s3TablesBucketName: '<your-table-bucket-name>',
s3TablesNamespace: 'aurora_cdc',
tables: ['orders', 'products'],
tableKeys: { orders: 'order_id', products: 'product_id' },
// Firehose - general purpose S3 bucket for failed record backup
firehoseBackupBucket: '<your-backup-bucket-name>',
};
Key configuration notes:
auroraSecurityGroupId. The security group attached to your Aurora cluster. The CDK creates an MSK security group with ingress rules allowing traffic from this security group, and a reverse rule allowing MSK Connect workers to reach Aurora on port 5432.
tableKeys. The primary key column for each table. Firehose uses these to match incoming records against existing rows for update and delete operations in the Iceberg tables.
Amazon MSK cluster (2x kafka.m5.large brokers) with dual authentication (IAM for Firehose, unauthenticated for Debezium), custom configuration with auto.create.topics.enable=true, security groups with ingress rules for Aurora and MSK Connect workers
CdcMskConnectIam
MSK Connect service execution role with permissions for Kafka cluster operations, VPC networking, S3 plugin access, and AWS Secrets Manager; Amazon CloudWatch Logs group for connector logs
CdcS3Tables
S3 table bucket, aurora_cdc namespace, two Iceberg tables (orders, products) with column schemas
CdcLambdaTransform
Lambda function for CDC event transformation and multi-table routing
Firehose delivery stream with MSK as source (private connectivity through AWS PrivateLink), Lambda processing, Apache Iceberg Tables as destination with two table configurations, and S3 backup bucket for failed records
The MSK cluster takes approximately 25 minutes to create. The Debezium connector takes approximately 5 minutes after the cluster is ready. You can monitor the deployment progress in the AWS CloudFormation console.
After the deployment completes, you can verify the resources in the AWS console. The S3 table bucket shows the two Iceberg tables in the aurora_cdc namespace.
Figure 2. S3 table bucket showing the orders and products Iceberg tables in the aurora_cdc namespace.
The Firehose delivery stream shows the MSK source, Lambda transformation, and Apache Iceberg Tables destination.
Figure 3. Amazon Data Firehose delivery stream with MSK source, Lambda transformation, and Apache Iceberg Tables destination.
The MSK cluster uses dual authentication (IAM for Firehose, unauthenticated for Debezium through TLS_PLAINTEXT), multi-VPC private connectivity for Firehose PrivateLink access, and auto.create.topics.enable=true so Debezium can create topics on first connect. VPC connectivity and the cluster resource policy are configured as CLI steps in Step 5.
Step 5: Enable MSK VPC connectivity, grant Lake Formation permissions, and apply MSK cluster policy
After the CDK deployment completes, enable multi-VPC private connectivity with IAM on the MSK cluster. Firehose requires this to create an AWS PrivateLink endpoint to the MSK brokers. This setting can’t be configured during cluster creation and must be applied as an update, which triggers a rolling broker restart (approximately 20–30 minutes).
# Get the cluster ARN and current version from the CdcMskCluster stack outputs
MSK_ARN=<msk-cluster-arn>
CLUSTER_VERSION=$(aws kafka describe-cluster-v2 \
    --cluster-arn $MSK_ARN \
    --region <your-region> \
    --query 'ClusterInfo.CurrentVersion' --output text)
# Enable VPC connectivity with IAM
aws kafka update-connectivity \
    --cluster-arn $MSK_ARN \
    --current-version $CLUSTER_VERSION \
    --connectivity-info '{"VpcConnectivity":{"ClientAuthentication":{"Sasl":{"Iam":{"Enabled":true}}}}}' \
    --region <your-region>
Wait for the cluster state to return to ACTIVE before proceeding:
Next, grant the Firehose IAM role permissions through AWS Lake Formation. S3 Tables uses a sub-catalog format for the CatalogId parameter, which differs from the standard AWS Glue Data Catalog. These permissions require a data lake administrator identity.
Grant database-level and table-level permissions to the Firehose role:
# Grant database-level permissions
aws lakeformation grant-permissions \
    --region <your-region> \
    --principal '{"DataLakePrincipalIdentifier": "<firehose-role-arn>"}' \
    --resource '{"Database": {"CatalogId": "<account-id>:s3tablescatalog/<table-bucket-name>", "Name": "aurora_cdc"}}' \
    --permissions '["ALL"]'
# Grant table-level permissions (wildcard for the tables in the namespace)
aws lakeformation grant-permissions \
    --region <your-region> \
    --principal '{"DataLakePrincipalIdentifier": "<firehose-role-arn>"}' \
    --resource '{"Table": {"CatalogId": "<account-id>:s3tablescatalog/<table-bucket-name>", "DatabaseName": "aurora_cdc", "TableWildcard": {}}}' \
    --permissions '["ALL"]'
Note the CatalogId format: <account-id>:s3tablescatalog/<table-bucket-name>. This is specific to S3 Tables and tells Lake Formation to look up permissions in the S3 Tables catalog rather than the default Glue Data Catalog. For more information, see Integrating Amazon S3 Tables with AWS analytics services.
Next, attach a resource-based policy to the MSK cluster that grants the Firehose service principal permission to create VPC connections:
You can find the <msk-cluster-arn> in the CdcMskCluster stack outputs from Step 4, and the <firehose-role-arn> in the CdcFirehoseRole stack outputs.
Step 6: Create the Debezium connector
With the MSK cluster running and Lake Formation permissions in place, create the Debezium connector using the MSK Connect API. The connector reads changes from Aurora PostgreSQL and publishes them to the MSK topic.
Firehose supports only one MSK topic per delivery stream, so each source table would otherwise need its own Firehose stream and VPC connection. To avoid this, the connector uses the Debezium ByLogicalTableRouter Single Message Transform (SMT) to route changes from multiple tables into a single topic (aurora.cdc.all-tables). The Lambda function then uses the source table name in each message to direct records to the correct Iceberg table. This single-topic pattern uses one Firehose stream for multiple tables, reducing cost and operational complexity.
First, retrieve the MSK bootstrap servers from the cluster:
The <msk-security-group-id> and <msk-connect-service-role-arn> can be found in the CdcMskCluster and CdcMskConnectIam stack outputs respectively. The ByLogicalTableRouterSingle Message Transform routes CDC events from the monitored tables into a single topic (aurora.cdc.all-tables).
Step 7: Verify the Debezium connector
After creating the connector, verify that it is running and has completed its initial snapshot.
You should see messages indicating the transition to streaming mode:
Finished exporting 0 records for table 'public.orders' (1 of 2 tables)
Finished exporting 0 records for table 'public.products' (2 of 2 tables)
Snapshot completed
Starting streaming
If the tables were empty when the connector started, the export count is 0. If you had existing data, the snapshot captures the existing rows as r (read) operations, which the Lambda function maps to insert operations in the Iceberg tables.
Verify that the Firehose delivery stream is active:
Insert test data into the Aurora PostgreSQL source tables. Each insert triggers a CDC event that flows through the pipeline: Aurora WAL to Debezium to MSK topic to Firehose to Lambda transform to S3 Tables.
This creates six records across two tables. Each record generates a Debezium CDC event with operation type c (create), which the Lambda function maps to an insert operation in the corresponding Iceberg table.
Step 9: Verify data delivery
Check the Firehose IncomingRecords metric to confirm records are flowing through the delivery stream:
You should see a Sum value of 6 or more. If the value is 0, wait another minute and retry. There can be a short delay between MSK topic delivery and Firehose metric reporting.
If records aren’t appearing, check the Firehose error output in the backup S3 bucket and the Lambda function’s CloudWatch Logs for transformation errors.
Step 10: Query data using Amazon Athena
With data delivered to S3 Tables, you can query the Iceberg tables using Amazon Athena. S3 Tables integrates with the AWS Glue Data Catalog as a sub-catalog, so you reference tables using the S3 Tables catalog format.
Tip: If records aren’t appearing in Athena, check the Firehose IncomingRecords CloudWatch metric and the Lambda function’s CloudWatch Logs for transformation errors.
Open the Athena console, select the AwsDataCatalog data source, and run the following queries:
SELECT * FROM "s3tablescatalog/<table-bucket-name>"."aurora_cdc"."products" LIMIT 10;
SELECT * FROM "s3tablescatalog/<table-bucket-name>"."aurora_cdc"."orders" LIMIT 10;
Replace <table-bucket-name> with your S3 table bucket name. You should see the records from the initial snapshot that Debezium captured when the connector started.
The following figures show the initial state of both tables as queried through Athena. At this point, the products table contains seven records and the orders table contains seven records, captured during the Debezium initial snapshot.
Figure 5. Initial state of the products table in Amazon Athena, showing seven records captured from Aurora PostgreSQL through the CDC pipeline.
Figure 6. Initial state of the orders table in Amazon Athena, showing seven records captured from Aurora PostgreSQL through the CDC pipeline.
Now test that update and delete operations propagate correctly. Run the following statements in Aurora:
-- Insert new records
INSERT INTO public.products (product_name, category, price, stock_quantity)
VALUES ('Bluetooth Speaker', 'Electronics', 129.99, 90), ('Standing Desk', 'Furniture', 799.99, 20);
INSERT INTO public.orders (customer_id, order_date, total_amount, status)
VALUES (201, '2026-04-03', 149.99, 'NEW'), (202, '2026-04-03', 249.50, 'NEW'), (203, '2026-04-03', 79.90, 'NEW');
-- Update existing records
UPDATE public.products SET stock_quantity = 30, price = 549.99 WHERE product_name = 'Ergonomic Chair';
UPDATE public.orders SET status = 'DELIVERED' WHERE order_id = 201;
-- Delete a record
DELETE FROM public.products WHERE product_name = 'Test Widget';
Wait for the changes to propagate through the pipeline, then query Athena again. The following figures show the results after the insert, update, and delete operations have been applied.
In the products table, the Test Widget record (product_id 100) is no longer present because it was removed by the delete operation. The Ergonomic Chair row now reflects the updated price (549.99) and stock quantity (30). Two new records, Bluetooth Speaker and Standing Desk, appear with a later created_at timestamp, confirming they were inserted after the initial snapshot.
Figure 7. Products table after CDC operations. The Ergonomic Chair, Headphones, and Desk Lamp rows reflect updated values. Bluetooth Speaker and Standing Desk are newly inserted records. The Test Widget record has been removed by the delete operation.
In the orders table, order 100 now shows a status of SHIPPED and order 201 shows DELIVERED, reflecting the update operations. Three new orders (301, 302, 303) appear with status NEW and a later timestamp, confirming they were inserted after the initial load.
Figure 8. Orders table after CDC operations. Orders 100 and 201 reflect updated status values. Orders 301, 302, and 303 are newly inserted records.
This confirms that the pipeline correctly handles the three CDC operation types: inserts, updates, and deletes are captured from the Aurora WAL by Debezium, routed through the single MSK topic, transformed by the Lambda function, and applied as row-level Iceberg operations by Firehose.
S3 Tables handles compaction and snapshot management for Iceberg tables automatically, including compaction of small data files and expiration of old snapshots. You don’t need to run manual maintenance operations.
You can also use Iceberg’s time travel capability to query the table as it existed before the updates:
SELECT * FROM "s3tablescatalog/<table-bucket-name>"."aurora_cdc"."orders"
FOR TIMESTAMP AS OF current_timestamp - interval '5' minute;
This returns the original data before the update, demonstrating the time travel capability that Apache Iceberg provides through S3 Tables.
Cleaning up
To avoid ongoing charges, delete the resources in reverse dependency order.
Delete the CDK stacks:
cd cdk
npx cdk --app "npx ts-node bin/app-v2.ts" destroy --all
Delete the Debezium custom plugin and worker configuration that were created through the AWS CLI in Step 2:
Clean up the Aurora PostgreSQL replication resources:
SELECT pg_drop_replication_slot('debezium_slot');
DROP PUBLICATION dbz_publication;
Important: The replication slot (debezium_slot) was created automatically by Debezium. If you plan to redeploy the pipeline later, you don’t need to drop the slot and publication. However, the replication slot continues to retain WAL segments while the connector isn’t running, which can increase storage usage on the Aurora cluster. The MSK cluster is the largest cost component of this solution and can’t be paused. It can only be deleted and recreated.
Conclusion
In this post, we showed you how to build a near real-time CDC pipeline from Aurora PostgreSQL to Apache Iceberg tables in Amazon S3 Tables. The key architectural decisions include:
Single-topic routing with multi-table delivery. The Debezium ByLogicalTableRouter SMT routes CDC events from multiple tables through one MSK topic, and the Lambda otfMetadata routing directs each record to the correct Iceberg table. This reduces VPC connection costs by using a single Firehose stream for inserts, updates, and deletes across multiple destination tables.
Fully managed CDC pipeline. MSK Connect runs Debezium, Firehose handles delivery with automatic retries, and S3 Tables manages Iceberg compaction and snapshots. The Lambda transform preserves CDC semantics by mapping Debezium operations to Iceberg row-level operations.
Governed lakehouse access. Lake Formation controls fine-grained access to the Iceberg tables, and data from multiple isolated Aurora clusters can be unified in a single S3 Tables namespace for cross-domain analytics.
Infrastructure as code. Six AWS CDK stacks deploy the core pipeline, with Lake Formation permissions, MSK cluster policy, and Debezium connector configured through documented CLI steps.
Healthcare providers manage millions of paper medical records that remain disconnected from modern clinical systems. Clinicians make decisions without full patient histories, organizations spend millions on manual data entry, and critical information stays trapped in formats that modern applications can’t read. The technical challenge is clear: how do you transform unstructured, scanned documents into standardized, interoperable health data at scale, without building custom machine learning (ML) models or hand-coding document parsers for every form type.
In this post, you learn how to build an automated, serverless pipeline that converts scanned PDF medical records into FHIR R4-compliant data using Amazon Bedrock Data Automation and AWS HealthLake. We walk through the architecture, explain how each AWS service connects to the next, show you what the pipeline looks like when it runs, and get you deployed in under 20 minutes. For advanced configuration, troubleshooting, and customization options, see the GitHub repository.
The challenge with paper medical records
Healthcare organizations face a compounding problem. Paper records don’t only create storage challenges, they create care gaps. When a patient arrives at a new facility, clinicians often proceed with incomplete information because retrieving and interpreting historical records takes too long. Manual digitization is expensive, error-prone, and doesn’t scale.
The solution requires more than scanning documents. It requires extracting structured, clinically meaningful data and storing it in a format that integrates with existing systems. That’s where Fast Healthcare Interoperability Resources (FHIR) comes in. FHIR is the healthcare industry’s standard for exchanging electronic health information.
Solution overview
This solution uses an event-driven, serverless architecture to automate the full journey from PDF upload to queryable FHIR data. No custom machine learning models or manual template configuration are required.
AWS services used:
Amazon Bedrock Data Automation (BDA): Extracts over 50 structured clinical fields from scanned PDFs using advanced AI capabilities, including patient demographics, diagnoses with ICD-10 codes, medications, vital signs, and lab results.
AWS Lambda: Two serverless functions orchestrate the pipeline: a BDA Trigger function that fires when a PDF is uploaded, and a FHIR Processor function that converts extracted JSON into FHIR R4 format.
Amazon Simple Storage Service (Amazon S3): Input and output buckets with event notifications drive the pipeline automatically, with no polling or scheduled jobs required.
AWS HealthLake: A FHIR R4-compliant, HIPAA-eligible data store that validates, indexes, and exposes data through standard FHIR API endpoints.
AWS CloudFormation: Provisions the entire infrastructure as code in a single automated deployment (approximately 15–20 minutes).
Amazon CloudWatch and AWS CloudTrail: Provide end-to-end monitoring, logging, and audit trails across all pipeline components.
Important: This solution is a demonstration sample designed for use with synthetic data only. It’s not production-ready for real Protected Health Information (PHI) without additional HIPAA security controls. See the Security considerations section before deploying in any environment with real patient data.
Architecture
Figure 1: End-to-end architecture showing the event-driven pipeline from PDF upload to FHIR-compliant data storage
The pipeline runs in three phases, each building on the last.
Phase 1: Infrastructure deployment
AWS CloudFormation provisions all required resources in a single stack: Amazon S3 input and output buckets, two Lambda functions, AWS Identity and Access Management (IAM) roles with least-privilege permissions, AWS KMS keys, CloudWatch log groups, and an AWS HealthLake FHIR R4 datastore. The entire environment, including all service-to-service permissions, is version-controlled and repeatable.
Phase 2: Event-driven data processing
The processing pipeline is fully event-driven. No scheduler or orchestration service is required. Each step triggers the next automatically:
PDF Upload → S3 Input Bucket
S3 Event → Triggers BDA Lambda function
BDA Processing → Extracts over 50 clinical fields with confidence scores
JSON Storage → S3 Output Bucket
S3 Event → Triggers FHIR Processor Lambda function
HealthLake Import → Automatic NDJSON ingestion and validation
FHIR API Access → Query using HealthLake endpoints
Phase 3: Query and analytics
After the data is in AWS HealthLake, it’s immediately queryable using standard FHIR R4 API endpoints. Python scripts authenticate using AWS Signature Version 4 (SigV4) and support searches by patient, condition, medication, or lab result type.
How the services connect
Understanding the service interconnections is key to customizing or extending this solution.
Amazon S3 as the pipeline backbone
Amazon S3 plays a dual role: it’s both the entry point for raw PDFs and the handoff layer between processing stages. Amazon S3 event notifications remove the need for polling. When a PDF lands in the input bucket, the BDA Lambda fires immediately. When BDA writes its JSON output to the output bucket, the FHIR Processor Lambda fires automatically. This decoupled design means that each stage can scale independently.
Amazon Bedrock Data Automation as the intelligence layer
BDA serves as the intelligence layer. When Lambda triggers the extraction job, BDA retrieves the PDF from Amazon S3 and applies a custom medical blueprint, which is a schema defining the over 50 clinical fields to extract. The service understands document structure without requiring templates or training data. Each extracted field is returned with a confidence score (0.0–1.0), which the FHIR Processor Lambda uses to apply validation thresholds before conversion.
AWS Lambda as the transformation layer
The two Lambda functions are intentionally narrow in scope:
The BDA Trigger Lambda receives the Amazon S3 event, constructs the BDA API call, and submits the processing job.
The FHIR Processor Lambda reads BDA’s JSON output, maps each extracted field to the appropriate FHIR R4 resource type, assembles a FHIR Bundle, exports it as NDJSON, and triggers an AWS HealthLake import job.
This separation of concerns makes each function independently testable and replaceable.
AWS HealthLake as the FHIR data store
AWS HealthLake receives the NDJSON import, validates each resource against the FHIR R4 specification, creates relationships between resources (for example, linking Condition resources to their Patient), indexes data for efficient querying, and generates unique FHIR resource IDs. The result is a fully queryable FHIR data store accessible through authenticated API calls.
IAM roles as the security fabric
Each service communicates with the next using IAM roles with least-privilege permissions. There are no hardcoded credentials and no overly broad policies. Lambda functions assume roles that grant only the specific actions they need (for example, bedrock-data-automation:InvokeDataAutomationAsync and s3:GetObject for the BDA Trigger Lambda).
Walkthrough
This walkthrough takes you from prerequisites through deployment and verification.
Prerequisites
Before deploying, confirm you have the following:
Required software:
Python 3.10 or later.
Poetry (Python dependency management).
AWS Command Line Interface (AWS CLI) configured with appropriate credentials.
You need IAM permissions for the following services:
Amazon Bedrock Data Automation.
AWS CloudFormation (create, update, and delete stacks).
Amazon S3 (create buckets, upload and download objects).
AWS Lambda (create and update functions).
AWS Identity and Access Management (IAM) (create roles and policies).
AWS HealthLake (create data stores).
Supported AWS Regions:
This solution currently supports us-east-1 (US East N. Virginia) and us-west-2 (US West Oregon) only. These are the Regions where Amazon Bedrock Data Automation is available.
Deploy the pipeline
Deployment takes approximately 15–20 minutes. Run the following four commands to go from zero to a fully deployed pipeline:
# 1. Clone the repository and install dependencies
git clone <repository-url>
cd Medical-Record-Digitization-and-FHIR-Integration-Pipeline
poetry install

# 2. Configure your environment
poetry run python src/utils/setup_env.py

# 3. Deploy the CloudFormation stack (approximately 15 minutes)
poetry run python src/automation/deploy.py

# 4. Verify deployment
aws cloudformation describe-stacks \
  --stack-name bda-medical-records-stack \
  --query 'Stacks[0].StackStatus'
# Expected output: "CREATE_COMPLETE"
The deployment creates the following resources:
Amazon Bedrock Data Automation blueprint and project (custom medical records schema with over 50 fields).
Amazon S3 input and output buckets with automatic event notifications.
Two AWS Lambda functions (BDA Trigger and FHIR Processor).
AWS HealthLake FHIR R4 data store.
AWS Identity and Access Management (IAM) roles and policies with least-privilege permissions.
Amazon CloudWatch log groups for all Lambda executions.
For manual environment configuration, advanced deployment options, and troubleshooting, see the GitHub repository.
See it in action
After it’s deployed, upload a sample medical record to trigger the full pipeline. You can use the sample provided in the GitHub repository.
# Get your input bucket name from the CloudFormation stack output
INPUT_BUCKET=$(aws cloudformation describe-stacks \
  --stack-name bda-medical-records-stack \
  --query 'Stacks[0].Outputs[?OutputKey==`InputBucketName`].OutputValue' \
  --output text)

# Upload a sample PDF (use the synthetic records included in the repository)
aws s3 cp samples/medical-record-sample.pdf s3://$INPUT_BUCKET/

# Track BDA processing jobs
poetry run python src/utils/track_bda_jobs.py
Within 2–3 minutes, Amazon Bedrock Data Automation processes the PDF and the FHIR Processor Lambda imports the results into HealthLake. View the extracted data:
After ingestion, query your data using the interactive FHIR query interface:
poetry run python src/utils/query_medical_data.py
Supported FHIR query patterns:
# Search by patient name
Patient?name=Wilkins

# Get conditions for a specific patient
Condition?patient=Patient/47ef817a-9826-4498-b693-2af5eb2b5250

# Get lab results only
Observation?category=laboratory

# Get vital signs only
Observation?category=vital-signs

# Get all medications
MedicationRequest
This is a demonstration sample for synthetic data only. Do not use with real Protected Health Information (PHI) without implementing the controls listed in the following sections.
Security controls included in this sample:
IAM roles with least-privilege permissions.
Amazon S3 bucket access controls (private by default).
AWS KMS encryption for AWS HealthLake data at rest.
AWS service-to-service authorization using IAM roles.
Amazon CloudWatch logging for audit trails.
Additional controls required for production PHI workloads:
AWS HealthLake is a HIPAA Eligible Service. Customers must review the AWS Shared Responsibility Model to understand their security and compliance obligations. Before processing real patient data, implement the following:
AWS Business Associate Addendum (BAA): Required under HIPAA before processing PHI on AWS.
Amazon Virtual Private Cloud (Amazon VPC) isolation: Lambda functions and AWS HealthLake in private subnets with AWS PrivateLink.
The following estimates apply to testing with approximately 100 medical records per month in the US West (Oregon) Region:
Service
Usage
Estimated monthly cost
Amazon Bedrock Data Automation
100 pages (approximately $0.20–$0.30/page)
$20–$30
AWS HealthLake
5 GB storage + 100 queries
$15–$20
AWS Lambda
200 invocations (512 MB, approximately 30s avg)
$5–$10
Amazon S3
1 GB storage + 200 requests
$1–$2
AWS KMS
1 customer managed key
$1
Total approximately $50–$100/month
For production workloads processing 10,000 records per month, expect costs in the range of $2,000–$3,000/month. The primary cost drivers are BDA (charged per page), HealthLake (charged per search request), and VPC endpoints (hourly PrivateLink charges in production deployments).
Cost optimization tips:
Delete the CloudFormation stack when not actively testing: aws cloudformation delete-stack --stack-name bda-medical-records-stack.
Set up AWS Budgets alerts to catch unexpected costs early.
Monitor Lambda duration in CloudWatch to optimize function execution time.
Clean up
To avoid ongoing charges, delete the CloudFormation stack when you’re done:
For cleanup of manually created Amazon Bedrock Data Automation projects and S3 bucket contents, see the GitHub repository.
What’s next
After you deploy, you can extend this foundation to:
Integrate with existing electronic health records (EHR) systems through FHIR APIs.
Build analytics dashboards using Amazon Quick Sight.
Add natural language search with Amazon Kendra.
Add Amazon Simple Queue Service (Amazon SQS) as a buffer between Amazon S3 events and the BDA Trigger Lambda to handle burst uploads and manage BDA concurrency limits at scale.
Orchestrate with AWS Step Functions for error handling, retry logic, and routing low-confidence extractions to human review.
Implement real-time, high-volume processing with Amazon Kinesis Data Streams for continuous ingestion from multiple sources.
Conclusion
In this post, you saw how Amazon Bedrock Data Automation, AWS Lambda, Amazon S3, and AWS HealthLake work together to automate the transformation of scanned medical records into FHIR R4-compliant data. The event-driven architecture removes manual data entry, scales without custom machine learning models, and makes historical records accessible to modern care delivery systems.
Key takeaways:
Amazon Bedrock Data Automation extracts over 50 structured clinical fields from PDFs without template configuration.
AWS Lambda orchestrates the pipeline with two focused, event-driven functions.
Amazon S3 event notifications decouple each stage, so each can scale independently.
AWS HealthLake validates, indexes, and exposes FHIR R4 data through standard APIs.
Security controls are the customer’s responsibility under the AWS Shared Responsibility Model.
To explore the full source code, advanced configuration options, and customization guidance, visit the GitHub repository.
Additional resources
For more information, see the following additional resources:
This solution is intended for educational purposes using synthetic data. Review the security considerations and consult your compliance team before deploying in any environment with real patient data.
Upgrading Apache Spark applications across major versions means tracking down breaking changes, manually debugging failures from log files, and running repeated test cycles. This process can stretch across weeks for complex code bases.
In this post, we walk through a hands-on PySpark migration from Spark 3.5 to Spark 4.0 on Amazon EMR Serverless, using the AWS Spark Upgrade Agent. You’ll see how the agent iteratively validates your application on a live Amazon EMR Serverless application, automatically diagnosing and resolving failures from Amazon CloudWatch logs until the job succeeds. By the end, you have a multi-pipeline PySpark application running on Spark 4.0 with four distinct breaking changes resolved. The fixes include configuration key removals, codec renames, and stricter charset validation, all driven through natural language interaction in the Integrated Development Environment (IDE).
This is part 2 of a three-part series on how the AWS Spark Upgrade Agent can automate and simplify Spark upgrades.
In Part 1, we introduced the agent’s architecture and capabilities. This post walks through a complete PySpark migration from Spark 3.5 to Spark 4.0 on Amazon EMR Serverless.
In the sections that follow, you will set up the prerequisites and infrastructure, explore the sample application, run the iterative validation workflow on EMR Serverless, review data quality results, and generate a comprehensive upgrade summary.
Note: Because this upgrade is performed using the AWS Spark Upgrade Agent Model Context Protocol (MCP) server, an agentic artificial intelligence (AI) system, the agent might take different paths to reach the same successful outcome. The workflow demonstrated here represents one successful upgrade path. The key takeaway is the end-to-end workflow: generating an upgrade plan, iteratively validating on Amazon EMR Serverless, and producing a comprehensive upgrade summary.
1. Prerequisites and setup
This section covers the tools, infrastructure, and IDE configuration you need before starting the upgrade. To follow along, you need an AWS account with an AWS Identity and Access Management (AWS IAM) user or role that has permissions to deploy AWS CloudFormation stacks, create AWS IAM roles and policies, and create Amazon EMR Serverless applications. Intermediate knowledge of AWS Command Line Interface (AWS CLI), AWS CloudFormation, and Python is helpful.
1.1 Install Kiro CLI and local tools
In this post, we use Kiro CLI to demonstrate the upgrade workflow. You can use an MCP-compatible IDE or framework. Examples include VS Code with Cline, Cursor, Windsurf, and Claude Desktop, among others. To follow along with Kiro CLI, install it on your workstation. For more details on the installation and setup, refer to Setup for Upgrade Agent:
curl -fsSL https://cli.kiro.dev/install | bash
Run the following command and use your builder ID to log in:
kiro-cli login --use-device-flow
With the Kiro CLI installed and logged in, rather than installing the remaining tools manually, use Kiro CLI to set up and verify your prerequisites with the following prompt:
kiro-cli chat
> Install AWS CLI, Python 3.10, and uv on my system if they are not already installed
Output of AWS CLI and local tools install step.
These tools are needed for the upgrade workflow:
AWS CLI: Configured with a profile that has permissions to assume the AWS Identity and Access Management (AWS IAM) role created following.
Python 3.10+: Required to match the EMR 8.0 runtime.
Two AWS CloudFormation stacks create the required resources: an AWS IAM role, an Amazon Simple Storage Service (Amazon S3) staging bucket, an Amazon EMR Serverless application (Spark 4.0.1), and its execution role.
Stack 1 – AWS IAM role and Amazon S3 staging bucket:
The spark-upgrade-mcp-setup template creates the AWS IAM role and Amazon S3 staging bucket required by the upgrade agent. Choose the Launch Stack button for your Region. For additional Regions, see the full region list.
After deployment, open the AWS CloudFormation Outputs tab, copy the ExportCommand value, and run it in your terminal. This sets SMUS_MCP_REGION, IAM_ROLE, and STAGING_BUCKET_PATH automatically.
aws configure set profile.spark-upgrade-profile.role_arn ${IAM_ROLE}
aws configure set profile.spark-upgrade-profile.source_profile default
aws configure set profile.spark-upgrade-profile.region ${SMUS_MCP_REGION}
This creates two Amazon EMR Serverless applications: a source (Spark 3.5.0) for data quality baseline and a target (Spark 4.0.1) for upgrade validation, with a shared execution role. Both applications auto-stop after 15 minutes of idle time, so there is no cost when not in use. To upgrade between different Spark versions, override SourceReleaseLabel and TargetReleaseLabel with your target Amazon EMR release labels.
After the stack completes deployment, note the outputs:
For other MCP clients, refer to your IDE’s MCP configuration documentation and use the same server parameters shown previously.
Verify the connection: Start Kiro CLI and confirm the spark-upgrade tools are loaded:
$ kiro-cli chat
...
spark-upgrade (MCP):
- generate_spark_upgrade_plan          * not trusted
- update_build_configuration           * not trusted
- fix_upgrade_failure                  * not trusted
- run_validation_job                   * not trusted
- check_job_status                     * not trusted
...
Tip: After Kiro CLI and the MCP server are configured, you can ask the agent to verify your setup. For example: “Check if I have AWS CLI, Python 3.10+, and uv installed, and confirm the spark-upgrade MCP server is connected.”
Output showing the status of each tool, AWS CLI, and MCP server.
Tip: Trust mode vs. confirm mode: When running the upgrade agent in Kiro CLI, you have two options:
Trust mode: Type t when prompted to approve a tool. The agent auto-approves subsequent uses of that tool without asking for confirmation. You can also use /tools trust-all to trust every tool at once for a fully autonomous experience.
Confirm mode: Type y for each individual tool invocation. This lets you review, verify, and approve every action before the agent runs it. If this is your first time using the agent, use confirm mode for full visibility.
2. Hands-on PySpark upgrade from Spark 3.5 to Spark 4.0
This section walks through the complete migration of a representative PySpark application from Amazon EMR Serverless 7.0.0 (Spark 3.5.0) to EMR Serverless with the emr-spark-8.0-preview release label (Spark 4.0.1), using the global_logistics_platform sample.
2.1 Sample project: global logistics platform
The sample application is a multi-domain PySpark data processing application with three pipelines:
Fleet management: Processes vehicle telemetry data (GPS tracking, fuel consumption, driver behavior scoring) using window functions, lag/lead operations, and statistical aggregations. Writes Parquet with lz4raw compression.
International shipping: Handles cross-border shipment documents with multi-language address standardization using character encoding functions (encode/decode with charsets like Shift_JIS, GB2312, EUC-KR), and processes carrier manifests with ISO-8859-1 encoding.
Historical compliance: Processes regulatory audit records spanning centuries (including pre-1582 Julian calendar dates), requiring legacy datetime rebasing for Parquet writes.
Before diving into the upgrade, here are the four specific breaking changes present in this code base that the agent discovers and resolves entirely through runtime validation:
#
Incompatibility
File(s)
1
Legacy Parquet configuration key removed:spark.sql.legacy.parquet.datetimeRebaseModeInWrite removed in Spark 4.0. Must use spark.sql.parquet.datetimeRebaseModeInWrite.
spark_config.py
2
Parquet compression codec rename:lz4raw codec renamed to lz4_raw in Spark 4.0.
telemetry_processor.py
3
Stricter charset encoding validation: Spark 4.0 tightened encode() behavior. Encoding CJK (Chinese, Japanese, Korean) characters to ISO-8859-1 now throws MALFORMED_CHARACTER_CODING. In Spark 3.x this silently replaced unmappable chars with ?. Restored via spark.sql.legacy.codingErrorAction.
spark_config.py
4
Character encoding restrictions:encode()/decode() in Spark 4.0 supports US-ASCII, ISO-8859-1, UTF-8, UTF-16BE, UTF-16LE, UTF-16, and UTF-32. Code uses Shift_JIS, GB2312, EUC-KR.
shipment_processor.py
The agent resolves each of these through iterative runtime validation on EMR Serverless: submitting the job, diagnosing failures from Amazon CloudWatch logs, applying fixes, and resubmitting until the job succeeds.
2.3 Step 1: Invoke the upgrade agent
Open the project in Kiro CLI and enter the following prompt:
Upgrade my Spark application in the current directory from EMR serverless version 7.0.0 to EMR serverless version 8.0.0.
Use Amazon EMR Serverless target app-id <YOUR-TARGET-APP-ID> and execution role
<YOUR-EXECUTION-ROLE-ARN> for validation.
Use source Amazon EMR Serverless app-id <YOUR-SOURCE-APP-ID> for data quality baseline.
Store artifacts at s3://${STAGING_BUCKET_PATH}/spark4-upgrade/python/
Enable data quality validation
Tip: The SourceApplicationId, TargetApplicationId, and ExecutionRoleArn are in the Outputs of the spark-emr-serverless-upgrade AWS CloudFormation stack you deployed in Section 1.2.
The agent invokes generate_spark_upgrade_plan, scans the project structure, identifies the Spark version mapping (EMR 7.0.0 → Spark 3.5.0, EMR 8.0.0 → Spark 4.0.1), and produces a structured upgrade plan with an Analysis ID for traceability.
The agent presents the plan and asks for confirmation. Type y to approve the tool invocation, or t to trust that tool for the rest of the session.
You have an option to save the plan as a local JSON file for future reference or to resume the upgrade at a later point, so go ahead and ask Kiro to save it locally. Provide the AWS CLI profile that you have configured on your system. Use the following prompt to provide these inputs:
Yes I would like to save the plan to a local file and use spark-upgrade-profile
2.4 Step 2: Build and package
The agent validates the Python project compiles successfully, then packages it for Amazon EMR Serverless deployment:
Runs py_compile on each .py file to verify syntax.
Creates src.zip containing the src/ directory (preserving the import structure used by from src.utils import ...).
Uploads src.zip, main.py, and sample input data to the Amazon S3 staging path.
# What the agent does behind the scenes:
zip -r src.zip src/
aws s3 cp main.py s3://<YOUR-BUCKET>/spark4-upgrade/python/<ANALYSIS-ID>/source/main.py
aws s3 cp src.zip s3://<YOUR-BUCKET>/spark4-upgrade/python/<ANALYSIS-ID>/source/src.zip
aws s3 cp data/sample/ s3://<YOUR-BUCKET>/spark4-upgrade/python/<ANALYSIS-ID>/input/ --recursive
No external dependencies (no requirements.txt), so no virtual environment is needed. If your project has external dependencies in a requirements.txt, the agent will package them into a virtual environment archive and include it in the EMR Serverless submission parameters.
2.5 Step 3: Data quality baseline on source application
Before migrating the code, the agent establishes a data quality baseline by running the original (pre-upgrade) code on the source Amazon EMR Serverless application (Spark 3.5.0 / EMR 7.0.0). This captures the expected output that the upgraded application must match.
The agent submits the job to the source application with data quality check enabled:
The agent monitors the source run via check_job_status until it completes successfully. This baseline output is stored for comparison after the target validation succeeds.
2.6 Step 4: Iterative runtime validation on target application
This is the core of the upgrade. The agent submits the unmodified application to the target Amazon EMR Serverless application (Spark 4.0.1), and every incompatibility is discovered, diagnosed, and fixed through runtime failures. The agent drives the entire fix cycle by submitting to EMR, reading errors from Amazon CloudWatch logs, applying fixes, rebuilding, and resubmitting.
The agent presents the proposed Amazon EMR Serverless job configuration for your review before each submission. Type y to approve.
The first submission fails immediately at SparkSession initialization:
org.apache.spark.sql.AnalysisException:
The SQL config 'spark.sql.legacy.parquet.datetimeRebaseModeInWrite' was removed
in the version 4.0.0. Use 'spark.sql.parquet.datetimeRebaseModeInWrite' instead.
The Historical Compliance pipeline configures spark.sql.legacy.parquet.datetimeRebaseModeInWrite for handling pre-1582 Julian calendar dates. Spark 4.0 removed the legacy. prefix from this configuration key.
The agent calls fix_upgrade_failure, which identifies the migration rule and recommends the fix:
File:src/utils/spark_config.py
# Before
.config("spark.sql.legacy.parquet.datetimeRebaseModeInWrite", "LEGACY")

# After
.config("spark.sql.parquet.datetimeRebaseModeInWrite", "LEGACY")
After applying the fix, the agent rebuilds src.zip, re-uploads to Amazon S3, and resubmits the job.
The resubmitted job fails with a new error, which confirms progress:
pyspark.errors.exceptions.captured.IllegalArgumentException:
[CODEC_NOT_AVAILABLE.WITH_AVAILABLE_CODECS_SUGGESTION]
The codec lz4raw is not available.
Available codecs are brotli, uncompressed, lzo, snappy, lz4_raw, none, zstd, lz4, gzip.
SQLSTATE: 56038
The Fleet Management pipeline’s telemetry_processor.py uses lz4raw as the Parquet compression codec. Spark 4.0 renamed this to lz4_raw (with an underscore).
org.apache.spark.SparkRuntimeException:
[MALFORMED_CHARACTER_CODING]
Invalid value found when performing `encode` with ISO-8859-1
SQLSTATE: 22000
The International Shipping pipeline’s process_carrier_manifests() method uses encode(..., 'ISO-8859-1') on data containing CJK (Chinese, Japanese, Korean) characters. Although ISO-8859-1 is in Spark 4.0’s supported charset list, it is a single-byte encoding that cannot represent CJK characters. In Spark 3.x, the Java charset encoder silently replaced unmappable characters with ?. Spark 4.0 tightened this behavior to throw MALFORMED_CHARACTER_CODING for unmappable characters.
The agent identifies the migration rule and adds a legacy compatibility configuration:
File:src/utils/spark_config.py
# Added to SparkSession builder
.config("spark.sql.legacy.codingErrorAction", "true")
This restores the Spark 3.x behavior where unmappable characters are silently replaced instead of throwing errors.
With the configuration added, the agent rebuilds and resubmits.
2.6.4 Fix 4: Character encoding restrictions (iteration 4)
The fourth submission fails with yet another encoding error:
org.apache.spark.SparkIllegalArgumentException:
[INVALID_PARAMETER_VALUE.CHARSET]
The value of parameter(s) `charset` in `encode` is invalid:
expects one of the iso-8859-1, us-ascii, utf-16, utf-16be, utf-16le, utf-32, utf-8,
but got Shift_JIS. SQLSTATE: 22023
The International Shipping pipeline’s standardize_addresses_with_charset() method uses Shift_JIS, GB2312, and EUC-KR charsets in encode()/decode() calls. Spark 4.0 restricts these functions to seven standard charsets. These regional charsets are not in the supported list.
The agent replaces the unsupported charsets with UTF-8:
The three pipelines (Fleet Management, International Shipping, and Historical Compliance) complete on EMR Serverless with the emr-spark-8.0-preview release label (Spark 4.0.1).
2.7 Summary of the iterative runtime validation
The runtime validation loop is the core value of the upgrade agent. Here’s the complete iteration history:
Each iteration follows the same cycle:
Failures that would normally require manual log analysis, root cause investigation, and code patching are resolved automatically by the agent in this workflow.
3. Data quality validation
With both the source baseline (Section 2.5) and the upgraded target run (Section 2.6) completed successfully, the agent performs data quality validation to verify the migration hasn’t changed your application’s output. This is the key advantage of including the source application in your upgrade prompt: the agent can compare outputs from both Spark versions side by side.
3.1 Data quality comparison
The agent invokes get_data_quality_summary to compare the outputs across four dimensions:
Schema validation: Confirms column names, data types, and column ordering match between source and target outputs.
Row count validation: Verifies no data loss or duplication during migration.
Nullability validation: Detects changes in null handling.
The preceding image shows the data quality summary.
Three of four checks pass cleanly. The statistical summary validation detects a mismatch in the shipper_address column of the customs_declarations output: the max and min summary values differ between source and target.
3.2 Understanding and resolving the mismatch
This mismatch is a direct consequence of Fix 4 (Section 2.6.4). The original code ran addresses through a Shift_JIS/GB2312/EUC-KR → UTF-8 roundtrip that produced garbled text, because the intermediate regional charset corrupted multi-byte UTF-8 characters. The upgraded code uses UTF-8 → UTF-8, preserving addresses faithfully. The mismatch reflects improved data quality, not a regression.
Schema, row counts, and nullability matched exactly: the difference is limited to string values that were previously garbled. No further action is needed. The upgraded application is production-ready.
Expected behavior: Character encoding migrations might change string values, although they preserve semantic meaning. When data quality validation reports mismatches, trace each one back to a specific code change. If the mismatch is explained by a required migration fix (as here), verify the new behavior is correct and document it. If a mismatch cannot be explained, investigate before promoting to production.
4. Upgrade summary
After the agent completes the entire upgrade workflow, it produces a comprehensive upgrade summary following a structured template. This summary lets you review the job configuration updates, code modifications with diffs and file references, relevant migration rules applied, and data quality validation status.
Here is the summary the agent produced for this upgrade:
Upgrade plan
Compile and build project with current Spark 3.5.0: validated that Python files compile successfully.
Run baseline validation on source EMR Serverless (00g4vhvt1lhtrs09) with Spark 3.5.0: established data quality baseline.
Run target validation on target EMR Serverless (00g4vhvt3np1bj09) with Spark 4.0.1: fixed 4 issues iteratively across 4 validation attempts.
Compare data quality between source and target runs: detected expected mismatch in shipper_address.
Generate and persist upgrade summary.
Upgrade result
Upgrade completed with data validation enabled. Data validation detected an expected mismatch in the shipper_address column because of the charset encoding migration from unsupported charsets (Shift_JIS, GB2312, EUC-KR) to UTF-8.
Dependency changes
No external dependencies were changed in this project (no requirements.txt).
Job configuration changes
Parquet datetime rebase configuration key renamed.
Migration rule: In Spark 4.0, the legacy datetime rebasing SQL configurations with the prefix spark.sql.legacy are removed. The SQL configuration spark.sql.legacy.parquet.datetimeRebaseModeInWrite was removed in the version 4.0.0. Use spark.sql.parquet.datetimeRebaseModeInWrite instead.
Legacy coding error action enabled.
Change: Added spark.sql.legacy.codingErrorAction set to true.
Migration rule: In Spark 4.0, the encode() and decode() functions raise MALFORMED_CHARACTER_CODING error when handling unmappable characters. In Spark 3.5 and earlier versions, these characters are replaced with garbled text. To restore the previous behavior, set spark.sql.legacy.codingErrorAction to true.
Error: [INVALID_PARAMETER_VALUE.CHARSET] charset in encode is invalid: expects one of iso-8859-1, us-ascii, utf-16, utf-16be, utf-16le, utf-32, utf-8, but got Shift_JIS.
Applied changes: src/domain/international_shipping/shipment_processor.py: Replaced Shift_JIS, GB2312, EUC-KR with UTF-8 for shipper and consignee address encoding.
Data mismatch: 1. The shipper_address column max summary value changed in customs_declarations output. This is expected because of the charset encoding migration from Shift_JIS/GB2312/EUC-KR to UTF-8. 2. The shipper_address column min summary value changed in customs_declarations output for the same expected cause.
5. Conclusion
The AWS Spark Upgrade Agent turns a traditionally time-consuming PySpark migration into an automated, iterative workflow. For the Global Logistics Platform sample, the agent identified and resolved four distinct Spark 4.0 breaking changes: legacy Parquet configuration key removal, compression codec renames, stricter charset encoding validation, and character encoding restrictions. Each fix was applied across three domain processors, through natural language interaction in the IDE.
Every incompatibility was discovered through runtime validation on Amazon EMR Serverless. The agent submitted the unmodified application to the target application, and each failure revealed the next breaking change:
The spark.sql.legacy.parquet.datetimeRebaseModeInWrite configuration removal, which crashes SparkSession initialization.
The lz4raw → lz4_raw codec rename, which fails when Parquet writes run.
ISO-8859-1 encoding of CJK characters: ISO-8859-1 is a valid Spark 4.0 charset, so the failure surfaces only when the code runs against real multi-language data, because Spark 4.0 tightened charset encoding validation to reject unmappable characters.
Shift_JIS/GB2312/EUC-KR charsets removed from Spark 4.0’s supported charset list entirely.
The agent diagnosed each error from Amazon CloudWatch logs, applied the fix, rebuilt, and resubmitted without manual intervention beyond approving each step. The data quality validation then confirmed that the upgraded application produces equivalent output on Spark 4.0.1: schema, row counts, and nullability matched exactly. The one difference, in the shipper_address column, resulted from the charset migration from regional encodings to UTF-8, which actually improved data quality by eliminating garbled text from incorrect encoding roundtrips. With each mismatch traced back to a specific, understood code change, the upgraded application is production-ready.
Building event-driven multi-tenant SaaS applications typically requires compute isolation between tenants to prevent data leakage, maintain security boundaries, and ensure compliance. Traditionally, you had to choose between two approaches: sharing execution environments across tenants (risking cross-tenant contamination of in-memory state) or managing separate Lambda functions per tenant (which introduces operational overhead, increasing costs, and complicating deployments). Both approaches required you to make trade-offs between security, operational complexity, and cost efficiency.
AWS Lambdatenant isolation mode with Event Source Mappings addresses this trade-off. This approach reduces operational complexity, improves your security posture, and removes the need to manage separate functions per tenant, all while maintaining strict compute-level isolation boundaries. You can now build event-driven architectures using services like Amazon SQS and Amazon EventBridge where each tenant’s workloads run in dedicated execution environments, but you manage only a single Lambda function.
In this post, you’ll learn how to propagate tenant identity from event payloads, implement IAM permissions for tenant-isolated invocations, apply validation strategies to verify tenant context, and use a lightweight routing mechanism that invokes tenant-isolated backends. Complete sample code demonstrating this pattern is available in the AWS samples repository.
Understanding Lambda tenant isolation mode
AWS Lambda tenant isolation mode extends Lambda’s execution model by introducing tenant-aware routing of invocations. Instead of reusing execution environments across all invocations of a function, Lambda associates each execution environment with a specific tenant identifier. When a new request is received, Lambda routes it to an existing environment for that specific tenant or creates a new one if none exists.
Figure 1. Using Lambda tenant isolation mode for compute isolation
This simplifies how you build multi-tenant SaaS systems, while maintaining isolation boundaries at the compute level. Execution environments are never shared across tenants but still reused within the same tenant for maximum efficiency. That means you can safely cache tenant-specific configurations, such as feature flags or database connection strings, without adding isolation logic manually in your code.
To use the tenant isolation mode, every invocation must include a tenant ID parameter. For synchronous, direct invocations, such as originating from Amazon API Gateway or AWS SDKs, you pass it using the X-Amz-Tenant-Id header, as described in the launch blog and service documentation. Lambda service uses this header to route the invocation to tenant-specific execution environments. Inside your function handler, the tenant ID is available using the context.tenantId property, so you can implement tenant-aware logic.
port const handler = async (event, context) => {
    const tenantId = context.tenantId;

    // Tenant-specific business logic here
    console.log(`Processing request for tenant: ${tenantId}`);
};
Figure 2. Accessing tenant ID from function handler.
When using API Gateway, you can extract the tenant ID value from incoming request metadata, such as HTTP headers, path parameters, query parameters, or JWT claims, and map it directly to the downstream X-Amz-Tenant-Id in the API Gateway integration request configuration. See the launch blog for detailed guidance.
This model works well for direct, synchronous invocations. However, many serverless applications rely on event-driven patterns, where Lambda is invoked through Event Source Mappings.
Using tenant isolation mode with event sources
Many serverless applications use event-driven architectures built on services like Amazon SQS, Amazon EventBridge, Amazon Kinesis, or Amazon DynamoDB Streams. In these cases, Lambda is invoked by an Event Source Mapping (ESM), which polls the event source and invokes your function when new events arrive.
With these services, you’ll commonly find the tenant identity embedded in the event payload or metadata – for example, in an SQS message body or EventBridge event detail. Each event source has its own payload schema. Below are example payloads when using SQS and EventBridge, where you can see the tenantId parameter present in the payload.
However, event sources don’t provide a built-in mechanism to map message properties to HTTP headers. As a result, if you try to invoke a function with tenant isolation mode enabled directly from an event source mapping, it fails because the tenant ID isn’t propagated as the X-Amz-Tenant-Id header. The following section describes how to address this and integrate ESMs with tenant-isolated Lambda functions.
Propagating tenant identity with Event Source Mappings
To propagate tenant identity from ESM messages, you can introduce a routing component – a lightweight Lambda function that sits between the event source and your tenant-isolated backend function. Your routing function receives events from the ESM, extracts the tenant ID from each message, and invokes your backend function using the Lambda Invoke API, passing the required X-Amz-Tenant-Id header. See the following diagram for an example architecture using SQS ESM.
Figure 3. Propagating tenant ID from SQS messages to Lambda with tenant isolation mode enabled
You don’t need to enable tenant isolation mode on the routing function itself – it acts as a stateless dispatcher. Your multi-tenant backend function, which contains your core business logic, runs with tenant isolation mode enabled and receives properly scoped, tenant-aware invocations. This pattern keeps tenant isolation at the backend layer while preserving a shared event ingestion model.
The following example illustrates a routing function that processes incoming SQS messages, extracts the tenant ID from each message body, and invokes your backend function with the appropriate tenant context. This example assumes MessageGroupId is used to carry the tenant identifier, which ensures messages from the same tenant are processed in order when you’re using FIFO queues.
export const handler = async (event) => {
    for (const record of event.Records) {
        const body = record.body;
        const messageGroupId = record.attributes?.MessageGroupId;

        const command = new InvokeCommand({
            FunctionName: BACKEND_FUNCTION_NAME,
            InvocationType: 'Event',
            TenantId: messageGroupId,
            Payload: Buffer.from(body)
        });

        await lambdaClient.send(command);
    }
}
Figure 4. Routing SQS messages to a Lambda function with tenant isolation mode enabled
The following example illustrates how you can achieve the same routing functionality when processing EventBridge events.
Figure 5. Routing EventBridge events to a Lambda function with tenant isolation mode enabled
IAM permissions
Your routing function’s execution role needs permission to:
Poll the event source: You can apply this policy either to your function execution role or as a resource policy on the event source itself.
Invoke the downstream backend function: Additionally, your router function requires the lambda:InvokeFunction permission scoped to your backend function ARN.
Below is an example execution role policy to allow the router function to poll from an SQS queue
Figure 6. IAM permissions used for implementing the tenant ID router function mechanism.
Best practices and considerations
When implementing the pattern described in this post, keep these important considerations in mind regarding validation, scaling, and overall system design.
Validate tenant identity before invocation. Tenant identity comes from event payloads, you shouldn’t automatically assume it’s trustworthy. Here’s how to protect your system:
Validate incoming payloads and reject messages with missing, malformed, or unauthorized tenant IDs at the routing layer before invoking your backend function
Maintain an authoritative tenant registry and validate incoming tenant IDs against it
Use dead-letter queues (DLQs) on your SQS queues to capture messages that fail validation for investigation and replay
When using EventBridge Pipes, use the enrichment step to validate or normalize tenant IDs before they reach your routing function
Enable partial batch response for applicable ESMs, such as SQS, so your routing function can report individual message failures without failing the entire batch
Plan for scaling considerations. Tenant isolation mode creates separate execution environments per tenant. This can increase the number of cold starts compared to shared environments. Each tenant consumes concurrency independently, so monitor your usage and request quota increases as your tenant base grows.
Optimize the routing function. Your routing function introduces an additional invocation segment. Use asynchronous invocation (InvocationType: ‘Event’) to reduce idle waiting time and size your function accordingly.
Understand permission boundaries. Tenants share your backend function’s execution role. If you need fine-grained per-tenant permissions, consider propagating tenant-scoped credentials (for example, using AWS STS AssumeRole) from the upstream segment.
Sample code
A complete, deployable sample project demonstrating this pattern – including SQS routing functions, a tenant-isolated backend function, and AWS SAM infrastructure – is available in this GitHub repository. Follow the instructions in README.md to provision the sample project in your account
Conclusion
Lambda tenant isolation mode introduces cross-tenant compute isolation for your multi-tenant SaaS applications by routing each invocation to a tenant-specific execution environment. When you combine this with event-driven architectures built on services like SQS, EventBridge, and Kinesis, the routing function pattern described in this post allows you to propagate tenant identity from event payloads and invoke your tenant-isolated backend with the correct context.
This approach extends tenant isolation mode to your asynchronous workloads without changing your core business logic. You retain per-tenant execution environment isolation while continuing to use Lambda’s native event source integrations, scaling model, and operational tooling. Together, these patterns provide you with a practical foundation for building secure, scalable, event-driven multi-tenant SaaS applications on AWS.
Next steps: Consider extending this pattern to other event sources like Kinesis Data Streams or DynamoDB Streams. You can also explore combining this approach with AWS Step Functions for orchestrating complex multi-tenant workflows while maintaining tenant isolation boundaries.
Running JMS applications on on-premises brokers or Apache ActiveMQ requires manual patching cycles, capacity planning for peak loads, and maintaining high availability across multiple data centers. With Amazon MQ version 4 and above, you can migrate your existing JMS applications without rewriting your messaging layer, removing weeks of rewrite work.
This post shows you how to migrate your JMS applications and walks through a complete setup, from creating the broker to sending and receiving messages. You will also see a real-world scenario: migrating an existing Apache ActiveMQ workload to an Amazon MQ broker running RabbitMQ. The post covers configuration changes, monitoring with Amazon CloudWatch, and validation steps to make sure that your migration succeeds.
Amazon MQ version 4 and above includes built-in support for the RabbitMQ JMS Client and the JMS Topic Exchange plugin. The RabbitMQ JMS Client and JMS Topic Exchange plugin work together, allowing your existing JMS applications to connect using familiar JMS APIs. You update the connection factory configuration and broker endpoint. Your business logic, message producers, consumers, and listeners stay exactly as written.
Understanding JMS and AMQP
How the RabbitMQ JMS Client works
Use the RabbitMQ JMS Client to connect your Java application to Amazon MQ. The client translates your JMS API calls (javax.jms or jakarta.jms) into AMQP 0-9-1 messages that the broker understands.
Advanced Message Queuing Protocol (AMQP) defines how messages are formatted and transmitted across the network at the wire level. This means that non-Java services can consume the same messages using native AMQP clients, making the protocol language-agnostic
JMS version support
Migrate at the JMS version that your application already uses. The client supports JMS 1.1, 2.0, and 3.1 (Jakarta Messaging), so you don’t need to upgrade your application code before migrating brokers. The client integrates with Spring Framework and Spring Boot applications without requiring custom bean factories or application context configuration.
Because the JMS abstraction layer sits between your application and the broker, most migrations require only a connection factory change, not a logic rewrite.
RabbitMQ JMS Topic Exchange plugin
Your existing publish/subscribe patterns work without client-side routing logic. The JMS Topic Exchange plugin adds server-side support for JMS topic semantics, handling topic routing and SQL-based message selection directly in the broker.
The plugin handles SQL-based message selection (JMS selectors like OrderType = `Electronics` AND Priority > 5) and topic hierarchies with wildcard pattern matching (* for single level, # for multiple levels). Your application uses standard JMS topic APIs (createTopic(), setMessageSelector()) without additional filtering logic.
Getting started
This walkthrough shows you how to set up Amazon MQ and connect your existing JMS application. You will create a broker, configure the connection factory, and send and receive messages.
Prerequisites
You need an existing JMS application built on Apache ActiveMQ or another JMS provider to migrate. If you don’t have one, you can still follow Steps 1–5 to create a broker and test the connection pattern. Before you begin, confirm that you have the following in place:
An active AWS account
AWS Command Line Interface (AWS CLI) installed. For instructions, see Installing the AWS CLI.
Java 11 or later installed on your local development environment.
An AWS Identity and Access Management (IAM) principal (user or role) with the AmazonMQFullAccess managed policy attached.
Maven or Gradle for dependency management.
Amazon MQ broker charges apply based on instance type and usage. Review the Amazon MQ pricing page before you start.
Step 1: Create an Amazon MQ for RabbitMQ broker
The following command creates a single-instance broker running RabbitMQ 4.2 on an mq.m7g.medium instance.
Replace <broker-name> with the name that you want to give to the broker. Replace <username> and <password> as described in the create-broker CLI documentation. After the command runs successfully, the command line displays the BrokerArn and BrokerId.
Note: This command creates a publicly accessible broker for demonstration purposes only. For production workloads, create brokers in private subnets within your VPC and restrict access using security groups. Don’t use the –publicly-accessible flag. For more information, see Security best practices for Amazon MQ.
Choose the dependency that matches your application’s current JMS version. If your imports reference javax.jms packages, use version 2.12.0. If your imports reference jakarta.jms packages (JMS 3.1 / Jakarta EE 9+), use version 3.4.0.
Store your broker credentials in AWS Secrets Manager before configuring the connection factory. This keeps credentials out of your source code and configuration files.
Publish/subscribe (topic) for one-to-many broadcast:
try (JMSContext context = connectionFactory.createContext()) {
	Topic topic = context.createTopic("orders.electronics");
	context.createProducer().setProperty("MessageType", "Broadcast").send(topic, "New electronics order received!");
	System.out.println("Published message to topic: orders.electronics");
}
Message properties(OrderType, MessageType) are JMS headers that consumers can use for filtering. These properties become AMQP message headers when transmitted to the broker.
Step 5: Receive messages asynchronously
To receive messages asynchronously, attach a MessageListener to a consumer. The listener fires each time a message arrives.
Queue consumer:
Asynchronous consumers process messages in a background thread without blocking your main application logic. The MessageListener callback fires each time a message arrives, allowing your application to handle messages as they’re delivered rather than polling with receive().
try (JMSContext context = connectionFactory.createContext()) {
	Queue queue = context.createQueue("orders");
	JMSConsumer consumer = context.createConsumer(queue);
	consumer.setMessageListener(message -> {
		if (message instanceof TextMessage) {
			try {
				System.out.println("Received: " + ((TextMessage) message).getText());
			} catch (JMSException e) {
				e.printStackTrace();
			}
		}
	});

	System.out.println("Listening for messages on queue: orders");

	// Keep the consumer active for 30 seconds
	Thread.sleep(30000);
}
The Thread.sleep(30000) call keeps the consumer active for 30 seconds.
Use case: Migrating an ActiveMQ Workload to Amazon MQ for RabbitMQ
Migrate your Apache ActiveMQ applications to Amazon MQ by updating four configuration points. Your business logic, message producers, consumers, and listeners stay exactly as written. This walkthrough uses a real JMS 1.1 application with a centralized broker configuration class to show precisely which lines change and which remain identical.
Apache ActiveMQ powers messaging infrastructure for thousands of Java applications worldwide. If you run JMS applications on ActiveMQ, you can migrate to Amazon MQ for RabbitMQ with minimal code changes. The following steps demonstrate a complete migration using an application that includes a centralized broker configuration class, a message producer, and a message consumer.
Step 1: Update the Maven dependency
Replace the ActiveMQ client dependencies with the RabbitMQ JMS client in your pom.xml. The rabbitmq-jms artifact includes the RabbitMQ AMQP client and JMS API as transitive dependencies, so a single entry replaces both ActiveMQ artifacts.
The rabbitmq-jms artifact pulls in the RabbitMQ AMQP client and the JMS API as transitive dependencies, so a single entry replaces both ActiveMQ artifacts.
Step 2: Update the broker configuration
If your application centralizes connection details in a shared configuration class, that class is the only file that needs to change. The queue name and everything else your application references remain the same.
Before (ActiveMQ):
// BrokerConfig.java - ActiveMQ version
public final class BrokerConfig {
	// OpenWire endpoint
	public static final String BROKER_URL = "tcp://localhost:61616";
	public static final String USERNAME = "[PASSWORD]";
	public static final String PASSWORD = "[PASSWORD]";
	public static final String QUEUE_NAME = "demo.queue";
	private BrokerConfig() {}}
After (Amazon MQ):
// BrokerConfig.java - Amazon MQ version

import com.fasterxml.jackson.core.type.TypeReference;import com.fasterxml.jackson.databind.ObjectMapper;
import software.amazon.awssdk.regions.Region;
import software.amazon.awssdk.services.secretsmanager.SecretsManagerClient;
import software.amazon.awssdk.services.secretsmanager.model.GetSecretValueRequest;
import software.amazon.awssdk.services.secretsmanager.model.GetSecretValueResponse;
import java.util.Map;

public final class BrokerConfig {
	// AMQPS endpoint (TLS required by Amazon MQ)
	public static final String BROKER_URL = "amqps://b-c8352341-ec91-4a78-ad9c-a57f23f235bb.mq.us-west-2.on.aws:5671";

	// Queue name carries over unchanged
	public static final String QUEUE_NAME = "demo.queue";

	// Secret name in AWS Secrets Manager
	private static final String SECRET_ID = "dev-rabbitmq";
	private static final Map<String, String> CREDENTIALS = loadCredentials();
	public static String getUsername() {return CREDENTIALS.get("username");}
	public static String getPassword() {return CREDENTIALS.get("password");}
	private static Map<String, String> loadCredentials() {
		try (SecretsManagerClient client = SecretsManagerClient.builder().region(Region.US_WEST_2).build()) {
			GetSecretValueResponse response = client.getSecretValue(GetSecretValueRequest.builder().secretId(SECRET_ID).build());
			ObjectMapper mapper = new ObjectMapper();
			return mapper.readValue(response.secretString(), new TypeReference<Map<String, String>>() {});
		} catch (Exception e) {
			throw new RuntimeException("Failed to load broker credentials from Secrets Manager", e);
		}
	}
	private BrokerConfig() {}}
Two things changed in this file compared to the ActiveMQ version: the protocol prefix (tcp:// to amqps://) and the host and port (OpenWire on 61616 to AMQP over TLS on 5671). The queue name is identical. Credentials are no longer stored as static string constants. Instead, loadCredentials() retrieves them from AWS Secrets Manager at startup, and getUsername() and getPassword() expose them to the rest of the application. This follows AWS security best practices and streamlines credential rotation.
Step 3: Update the message producer
The producer requires two changes: the import statement and the factory instantiation. Every JMS API call after the factory (createConnection, createSession, createProducer, send) is identical to the ActiveMQ version.
import com.rabbitmq.jms.admin.RMQConnectionFactory;
import javax.jms.*;

public class MessageProducer {

	public static void main(String[] args) {
		Connection connection = null;
		try {
			RMQConnectionFactory factory = new RMQConnectionFactory();
			factory.setUri(BrokerConfig.BROKER_URL);
			factory.setUsername(BrokerConfig.getUsername());
			factory.setPassword(BrokerConfig.getPassword());

			// Everything below this line is identical to the ActiveMQ version
			connection = factory.createConnection();
			connection.start();
			Session session = connection.createSession(false, Session.AUTO_ACKNOWLEDGE);
			Destination destination = session.createQueue(BrokerConfig.QUEUE_NAME);
			javax.jms.MessageProducer producer = session.createProducer(destination);
			producer.setDeliveryMode(DeliveryMode.PERSISTENT);
			for (int i = 1; i <= 5; i++) {
				TextMessage message = session.createTextMessage("Hello from Amazon MQ - message #" + i);
				producer.send(message);
				System.out.println("Sent: " + message.getText());
			}
			producer.close();
			session.close();
		} catch (JMSException e) {
			e.printStackTrace();
		} finally {
			if (connection != null) {
				try {
					connection.close();
				} catch (JMSException ignored) {}
			}
		}
	}
}
The import changes from org.apache.activemq.ActiveMQConnectionFactory to com.rabbitmq.jms.admin.RMQConnectionFactory. The factory construction switches from a constructor that accepts credentials and URL to a no-arg constructor with explicit setter calls. Credentials are now retrieved from AWS Secrets Manager through BrokerConfig.getUsername() and BrokerConfig.getPassword(). That is the complete change set for the producer.
Step 4: Update the message consumer
The consumer follows the same pattern as the producer. Swap the factory class and import, update the credential calls, and keep everything else.
import com.rabbitmq.jms.admin.RMQConnectionFactory;
import javax.jms.*;

public class MessageConsumer {
	public static void main(String[] args) {
		Connection connection = null;
		try {
			RMQConnectionFactory factory = new RMQConnectionFactory();
			factory.setUri(BrokerConfig.BROKER_URL);
			factory.setUsername(BrokerConfig.getUsername());
			factory.setPassword(BrokerConfig.getPassword());

			// Everything below this line is identical to the ActiveMQ version
			connection = factory.createConnection();
			connection.start();
			Session session = connection.createSession(false, Session.AUTO_ACKNOWLEDGE);
			Destination destination = session.createQueue(BrokerConfig.QUEUE_NAME);
			javax.jms.MessageConsumer consumer = session.createConsumer(destination);
			System.out.println("Waiting for messages on queue: " + BrokerConfig.QUEUE_NAME);
			Message message;
			while ((message = consumer.receive(10000)) != null) {
				if (message instanceof TextMessage) {
					TextMessage textMessage = (TextMessage) message;
					System.out.println("Received: " + textMessage.getText());
				}
			}
			consumer.close();
			session.close();
		} catch (JMSException e) {
			e.printStackTrace();
		} finally {
			if (connection != null) {
				try {
					connection.close();
				} catch (JMSException ignored) {}
			}
		}
	}
}
The import changes from org.apache.activemq.ActiveMQConnectionFactory to com.rabbitmq.jms.admin.RMQConnectionFactory. The factory construction switches to a no-arg constructor with explicit setter calls, and BrokerConfig.USERNAME / BrokerConfig.PASSWORD are replaced with BrokerConfig.getUsername() / BrokerConfig.getPassword(). The session creation, queue lookup, consumer setup, and message processing loop are identical to the ActiveMQ version.
Configuration
The following table summarizes the changes required when migrating from Apache ActiveMQ.
ActiveMQ
Amazon MQ for RabbitMQ
Maven dependency
activemq-client 5.18.6
rabbitmq-jms 2.12.0
Connection factory class
ActiveMQConnectionFactory
RMQConnectionFactory
Import package
org.apache.activemq
com.rabbitmq.jms.admin
Broker URL format
tcp://host:61616
amqps://broker-id.mq.region.on.aws:5671
Protocol
OpenWire
AMQP 0-9-1
Port
61616 (OpenWire)
5671 (AMQP over TLS)
TLS
Optional
Required
Credentials
Plain text / JNDI
AWS Secrets Manager (recommended)
Virtual host
N/A
/ (default)
JMS version support
JMS 1.1
JMS 1.1, 2.0, 3.1 (Jakarta)
Queue/Topic names
demo.queue
demo.queue (no change)
JMS API calls
Standard JMS 1.1
Standard JMS 1.1 (no change)
Validating the migration
Run your application against Amazon MQ for RabbitMQ in a staging environment before directing production traffic to the new broker. Verify that messages flow correctly, consumers process as expected, and no data loss occurs during cutover.
The RabbitMQ management console provides real-time visibility into broker operations. Access it through the ConsoleURL from your broker details. The console shows queue depths, consumer counts, and message rates. Use it during testing to identify routing or throughput issues before production deployment
The console displays jms.durable.queues and jms.durable.topic exchanges. The JMS client creates these automatically when your application creates queues and topics, so no manual exchange configuration is required.
Monitoring with Amazon CloudWatch
Amazon MQ publishes broker metrics to Amazon CloudWatch with no additional configuration needed. This gives you persistent monitoring and alerting that works alongside the rest of your AWS observability setup, beyond what the RabbitMQ management console provides in real time.
After your JMS messages reach the Amazon MQ for RabbitMQ broker, they’re transported as AMQP messages, which means standard RabbitMQ operational best practices apply. Keep queue depth low to avoid memory pressure and consumer lag. Follow message durability and reliability guidelines to prevent message loss during broker restarts. For connection management, review broker setup and connection best practices to avoid connection churn.
Set Amazon CloudWatch alarms on MessageCount and ConnectionCount first. A rising queue depth with a stable or dropping consumer count is an early signal of a processing bottleneck. A sudden drop in connections can indicate a client configuration issue that’s more straightforward to catch before it affects production traffic.
Clean up
To avoid ongoing charges after testing, delete the Amazon MQ broker and Secrets Manager secret using the AWS CLI.
Broker deletion is permanent and can’t be undone. Amazon MQ removes all messages, configurations, and user credentials. Leaving the broker running incurs hourly charges based on the instance type, plus storage costs for message data retained on the broker.
Conclusion
In this post, we walked you through how to migrate your JMS applications. We also walked through a complete setup, from creating the broker to sending and receiving messages. Migrating the broker is the straightforward part. The more significant question is what you do next. After your JMS application is running on Amazon MQ for RabbitMQ, you have access to native AMQP clients, which means non-Java services can start consuming the same messages without a JMS layer. A Java-centric messaging system becomes a shared event backbone that service can participate in. The migration is a starting point, not just a lift-and-shift.
It’s Monday morning and your VP pings you: “Revenue dropped 15 percent over the weekend. What happened?” The clock starts. You open the AWS Management Console, find the right Amazon Redshift cluster, open the query editor, and start hunting. Which database has the revenue data, analytics_db or reporting_db? Is the table called orders, transactions, or sales_events? You find it, but now you need the schema. Is the amount column total_amount, revenue, or order_value? 20 minutes in, you haven’t answered the question. You’ve been navigating infrastructure.
This scenario plays out daily across data teams, and it’s why the landscape is shifting. With AI agents entering the analytics workflow, a growing number of business users can now perform complex data analysis. They no longer need to file a ticket with the data engineering team and wait days for a response. The bottleneck is no longer SQL expertise. It’s the friction between having a question and getting an answer.
The Amazon Redshift MCP server paired with Kiro removes that friction. Instead of memorizing cluster endpoints, reverse-engineering schemas, and hand-writing SQL, you describe what you need in plain text and get results. That Monday morning question becomes a single sentence: “Show me daily revenue for the past two weeks, broken down by region.” Kiro finds the cluster, discovers the schema, writes the query, and returns the answer in seconds, not minutes.
In this post, you learn how to:
Install and configure Kiro with the Amazon Redshift MCP server.
Discover clusters, databases, and schemas using natural language.
Run analytical queries and cross-cluster comparisons conversationally.
Implement security best practices for production Amazon Redshift environments.
You can use Kiro in two forms: Kiro integrated development environment (IDE), a full desktop development environment, and Kiro command line interface (CLI), which brings the same AI capabilities directly to your terminal. The Redshift MCP server works with both. The CLI experience is particularly well suited for the conversational analytics workflow this post describes, because you can start querying your data warehouse from a terminal session without opening an IDE.
Important: Before using this integration with production Amazon Redshift environments, read the Security tips section. This section covers critical considerations around AWS Identity and Access Management (IAM) permissions and Kiro autonomy modes.
What is the Amazon Redshift MCP server?
The Model Context Protocol (MCP) is an open standard that provides AI agents with secure connections to external data sources and tools. The Amazon Redshift MCP server is an open source implementation that bridges the Kiro AI agent with your Amazon Redshift infrastructure.
With the Redshift MCP server, you can:
Automatically find both provisioned clusters and serverless workgroups with cluster discovery.
Browse databases, schemas, tables, and columns with metadata exploration.
Run SQL in READ ONLY mode with built-in safety protections with safe query execution.
Work with multiple clusters and workgroups simultaneously with multi-cluster support.
The server translates your natural language requests into the appropriate Amazon Redshift Data API calls and SQL queries. No manual endpoint configuration or SQL writing is required.
How the Redshift MCP server relates to the AWS MCP server
You might have noticed that AWS also offers the AWS MCP server (part of the Agent Toolkit for AWS), which provides broad access to AWS services, including the Redshift Data API. A common question is: if the AWS MCP server can already reach Redshift, why add a dedicated Redshift MCP server?
The two are complementary, not competing. The AWS MCP server gives Kiro general AWS capabilities (service decision guides, SDK usage guidance, troubleshooting skills, and access to AWS APIs). The Redshift MCP server adds a purpose-built analytics layer on top. It provides single-call query execution (compared to a minimum of three API calls for submit, poll, and fetch), read-only safety by default, transparent provisioned and serverless cluster handling, and dedicated metadata navigation tools. Upcoming features like query plan explanation, native identity propagation, cluster analysis, and UDF discovery will further extend this specialized layer.
You can use both together, or use the Amazon Redshift MCP server on its own. There’s no either-or requirement.
Setting it up
The following sections walk you through the installation and configuration process.
Prerequisites
Before you begin, make sure that you have:
On your machine:
Kiro IDE or Kiro CLI installed.
Python 3.10 or newer.
The uv package manager from Astral.
On AWS:
AWS credentials configured through the AWS Command Line Interface (AWS CLI), environment variables, or IAM roles.
At least one Amazon Redshift provisioned cluster or serverless workgroup.
IAM permissions for Amazon Redshift access (see the following section).
Step 1: Install the uv package manager
If you don’t have uv installed, run one of the following commands.
You also need database-level permissions: SELECT on tables you want to query, USAGE on schemas you want to explore, and connection access to the target databases.
Step 3: Configure the MCP server in Kiro
Open (or create) your Kiro MCP configuration file and add the Amazon Redshift server.
Tip: Replace AWS_PROFILE and AWS_DEFAULT_REGION with values matching your environment. If you use AWS_REGION instead of AWS_DEFAULT_REGION, AWS_REGION takes higher precedence.
In Kiro IDE, restart Kiro (or reconnect MCP servers from the MCP Server view in the Kiro feature panel). Then open the Kiro chat and enter the following prompt:
List my available Redshift clusters
If everything is configured correctly, Kiro discovers your clusters and lists them with details like cluster identifiers, status, node types, and endpoints.
Practical examples
The following scenarios show how Kiro and the Amazon Redshift MCP server work together in real-world workflows.
Tip: If you want Kiro to show the SQL that it executes alongside every result, tell it at the beginning of your session:
For every query you run against Amazon Redshift, show me the exact SQL you executed along with the results.
Kiro follows this instruction for the rest of the conversation. For a permanent setup, add this rule to a steering file (see the Tips section that follows) so you don’t need to repeat it. The following examples reflect this behavior.
Example 1: Discover and explore your infrastructure
Without Kiro: Log in to the AWS Management Console, navigate to Amazon Redshift, choose clusters, open the query editor, sign in to each database, and manually browse schemas.
With Kiro:
What Amazon Redshift clusters and serverless workgroups do I have?
Kiro responds with a structured overview:
Found two provisioned clusters and one serverless workgroup:
What databases and schemas exist in analytics-cluster?
Kiro uses the MCP metadata tools to explore the cluster. No SQL is needed for discovery:
Database: analytics_db (local)
information_schema — system schema
pg_catalog — system schema
public — default schema
sales — user-created schema
Database: dev (local)
information_schema — system schema
pg_catalog — system schema
public — default schema
The only user-created schema is sales in the analytics_db database.
Show me the tables in the sales schema of the analytics database
There are five base tables in analytics_db.sales:
customers
order_items
orders
products
returns
Describe the columns in the orders table
Column
Type
Nullable
order_id
INTEGER
NO
customer_id
INTEGER
NO
order_date
TIMESTAMP
NO
total_amount
numeric(12,2)
NO
status
VARCHAR(20)
YES
Each request builds on the previous context. Kiro remembers which cluster you’re exploring and navigates the hierarchy for you.
Example 2: On-demand data analysis in plain English
Without Kiro: Write SQL from scratch, guess at column names, run the query, fix syntax errors, iterate.
With Kiro:
Show me the top 10 customers by total purchase amount from the analytics-cluster,
including how many orders each customer placed
Kiro does the following:
Identifies the relevant cluster and database.
Explores the schema to find customer and order tables.
Understands the table relationships.
Generates and runs the appropriate SQL, showing you the query first.
Presents the results in a readable format.
The response includes the query and results:
Query executed:
SELECT
    c.customer_id,
    c.customer_name,
    COUNT(o.order_id) AS total_orders,
    SUM(o.total_amount) AS total_spent
FROM sales.customers c
JOIN sales.orders o ON c.customer_id = o.customer_id
GROUP BY c.customer_id, c.customer_name
ORDER BY total_spent DESC
LIMIT 10;
customer_id
customer_name
total_orders
total_spent
4821
Acme Corp
347
$1,284,500.00
1190
Globex Inc
289
$1,102,340.00
7734
Initech LLC
256
$987,210.00
…
…
…
…
You didn’t need to remember table names, column names, or join conditions. Kiro figured it out by exploring the metadata first. You can see exactly what it ran, copy the SQL, and reuse it.
Example 3: Cross-cluster data comparison
Without Kiro: Open two SQL clients, sign in to different clusters, run similar queries, manually compare results in a spreadsheet.
With Kiro:
Compare the total sales revenue and transaction counts between
analytics-cluster and etl-workgroup for the last quarter.
Are there any discrepancies?
Kiro queries both environments, aligns the results, and provides a comparison, showing every query it runs along the way.
Query executed on analytics-cluster:
SELECT
    COUNT(*) AS total_records,
    SUM(total_amount) AS total_revenue,
    COUNT(CASE WHEN order_date >= DATE_TRUNC('quarter', CURRENT_DATE - INTERVAL '3 months')
        THEN 1 END) AS q4_transactions
FROM sales.orders;
Query executed on etl-workgroup:
SELECT
    COUNT(*) AS total_records,
    SUM(total_amount) AS total_revenue,
    COUNT(CASE WHEN order_date >= DATE_TRUNC('quarter', CURRENT_DATE - INTERVAL '3 months')
        THEN 1 END) AS q4_transactions
FROM sales.orders;
Sales data comparison: Analytics vs ETL.
Metric
Analytics Cluster
ETL Workgroup
Status
Total Records
172,456
172,456
Match
Total Revenue
$110,765,431
$110,765,431
Match
Q4 Transactions
38,061
38,061
Match
Because both queries are visible, you can verify that Kiro compared the same metrics on both sides, with no hidden assumptions.
Example 4: Schema documentation on demand
Without Kiro: Manually document table structures in a wiki or spreadsheet. Documentation frequently falls out of date.
With Kiro:
Generate documentation for the tables in the sales schema of analytics-cluster.
Include column names, data types, and notable relationships.
Kiro explores every table using the discovery tools and produces structured documentation.
Table:sales.customers
Column
Type
Nullable
Description
customer_id
INTEGER
NO
Primary key
customer_name
VARCHAR(255)
NO
email
VARCHAR(255)
YES
created_at
TIMESTAMP
NO
Table:sales.orders
Column
Type
Nullable
Description
order_id
INTEGER
NO
Primary key
customer_id
INTEGER
NO
FK to customers
order_date
TIMESTAMP
NO
total_amount
numeric(12,2)
NO
status
VARCHAR(20)
YES
(continues for all tables in the schema…)
You can paste this directly into your team wiki or README, and anyone can rerun the same discovery flow to refresh the docs later.
Example 5: Troubleshooting data quality
Check the orders table in analytics-cluster for any NULL values
in the customer_id or total_amount columns.
How many records are affected?
Query executed:
SELECT
    COUNT(*) FILTER (WHERE customer_id IS NULL) AS null_customer_ids,
    COUNT(*) FILTER (WHERE total_amount IS NULL) AS null_total_amounts,
    COUNT(*) AS total_rows
FROM sales.orders;
Out of 172,456 rows: 0 NULL customer_ids, 3 NULL total_amounts.
Find duplicate order_ids in the sales.orders table and show me
a few examples with their timestamps
Query executed:
SELECT order_id, COUNT(*) AS occurrences, MIN(order_date) AS first_seen, MAX(order_date) AS last_seen
FROM sales.orders
GROUP BY order_id
HAVING COUNT(*) > 1
ORDER BY occurrences DESC
LIMIT 5;
Found two duplicate order_ids: order 88412 (two occurrences), order 91003 (two occurrences).
What's the date range of data in the events table?
Are there any gaps in the daily record counts?
Query executed:
WITH daily_counts AS (
    SELECT DATE(event_date) AS day, COUNT(*) AS record_count
    FROM sales.events
    GROUP BY DATE(event_date)
),
date_range AS (
    SELECT MIN(day) AS start_date, MAX(day) AS end_date FROM daily_counts
),
all_dates AS (
    SELECT (start_date + (n || ' days')::INTERVAL)::DATE AS day
    FROM date_range, generate_series(0, (end_date - start_date)) AS n
)
SELECT a.day AS missing_date
FROM all_dates a
LEFT JOIN daily_counts d ON a.day = d.day
WHERE d.day IS NULL
ORDER BY a.day;
Date range: 2024-01-01 to 2025-04-20. Found three missing dates: 2024-03-15, 2024-07-04, 2024-12-25 (likely holidays).
Every query is right there in the response. You can copy them into your own SQL client, modify them, or save them as reusable scripts.
Tips for getting the most out of Kiro and Redshift
Start with discovery. Begin each session by asking Kiro to list your clusters and explore the database structure. This gives the agent context for subsequent queries.
Be specific about which cluster. If you have multiple clusters, mention the cluster name in your request to avoid ambiguity.
Iterate gradually. Start with simple questions and build complexity. Ask for a count before asking for a full breakdown.
Use steering files for team conventions. Create a .kiro/steering/redshift.md file in your project with details about your cluster naming conventions, important schemas, and common query patterns. This gives Kiro persistent context about your environment.
Example steering file:
---
inclusion: auto
---

# Redshift Environment Context

## Clusters

- **analytics-cluster**: Primary analytics warehouse. Use database `analytics_db`.
- **etl-workgroup**: Serverless workgroup for ETL pipelines. Use database `staging_db`.

## Key Schemas

- `sales`: Customer transactions, orders, and revenue data
- `marketing`: Campaign performance and attribution data

## Conventions

- Always filter by `is_deleted = false` on soft-delete tables
- Date columns use `TIMESTAMP WITHOUT TIME ZONE` in UTC

## Query Transparency

- Always show the exact SQL query text being executed before or alongside the results.
  Users should be able to see, verify, and reuse every query that Kiro runs against Redshift.
That last Query Transparency rule is a small addition with a big impact. By default, Kiro might summarize results without showing the underlying SQL. Adding this steering instruction makes every query visible, which helps maintain consistent behavior across your data team and supports auditing, learning, and trust.
Use hooks for automation. Set up agent hooks to run common validation queries automatically. For example, trigger a data quality check whenever you edit a specific SQL file.
Verify important results. Always cross-check critical business findings with stakeholders before acting on them.
Security tips
When configured with least privilege IAM policies and Supervised mode, the Redshift MCP server provides multiple layers of protection. Under the AWS shared responsibility model, you are responsible for configuring access controls appropriately.
Safety layers at a glance
Data stays in your account. The MCP server runs locally, queries run inside your Amazon Redshift cluster, and no data is sent to third-party services.
Content not used for training. Enterprise users are excluded from service improvement usage. Free or individual tier users can opt out in Kiro settings.
Read-only by default. Every query is wrapped in a read-only transaction, preventing accidental writes.
Standard IAM controls. Kiro only gets permissions you’ve explicitly granted.
Supervised mode. Review each agent action before it’s applied in production environments.
Important caveat: The read-only enforcement only applies to queries routed through the MCP server’s execute_query tool. Kiro also has shell access. If your IAM credentials have write permissions, direct CLI calls (aws redshift-data execute-statement) bypass this guardrail entirely.
Takeaway: Use least privilege IAM policies (scoped to read and describe operations only) as your primary defense. Avoid broad policies like AdministratorAccess or AmazonRedshiftFullAccess. When IAM is properly scoped, even a direct CLI call cannot perform writes.
Verify Kiro’s output
Kiro is a powerful assistant, but it’s not infallible. Like any AI tool, it can misinterpret your intent, generate incorrect SQL, or present results that look plausible but are wrong. Examples include a misplaced join, a wrong filter, or an aggregation that silently excludes rows. This is especially important when working with production data where decisions have real business impact.
Treat Kiro’s output as a strong starting point, not a final answer. Review the SQL it generates before acting on the results. Use the Query Transparency steering rule (described in the Tips section) so you can see the exact query behind every result. When findings inform business decisions, validate them independently by running the query yourself, cross-checking with a colleague, or comparing against a known baseline.
Summary
Layer
What it protects against
MCP server read-only mode
Accidental writes through the MCP execute_query tool
Least privilege IAM policy
Write operations via any path, including direct CLI calls
Kiro Supervised mode
Unreviewed autonomous actions by the agent
Defense in depth: use these layers together for production environments.
What you can achieve with Kiro and Amazon Redshift
Before
Now you can
Switch between the console, SQL clients, and documentation
Use one interface for discovery, querying, and analysis
Memorize cluster endpoints, database names, and schemas
Ask in plain text and let Kiro discover the structure
Write SQL from scratch for every query
Describe what you want and get results
Manually compare data across clusters
Run single-sentence cross-cluster analysis
Schema documentation is frequently stale
Generate fresh docs on demand
Onboarding new analysts takes days
New team members can explore immediately
Every minute you spend hunting for a table name or debugging a SQL syntax error is a minute that you’re not spending on actual analysis. You can reduce that overhead by letting Kiro handle the mechanical parts (discovery, navigation, and query construction) so you can focus on the questions that matter to your business.
Cleaning up
If you created Amazon Redshift resources specifically for this walkthrough, or if you no longer need the MCP server integration, follow these steps. They help you avoid ongoing charges and remove the configuration.
Remove the MCP server configuration.
Detach the IAM policy.
Delete test Amazon Redshift resources (if applicable).
Uninstall uv (optional).
Conclusion
In this post, you learned how to set up Kiro with the Amazon Redshift MCP server to query your data warehouse using natural language. You explored cluster discovery, schema browsing, analytical queries, cross-cluster comparisons, and data quality checks, all without writing SQL from scratch or switching between tools.
Visit kiro.dev for Kiro’s full capabilities, including specs, hooks, and steering files.
As you get comfortable with the basics, try combining steering files with agent hooks to automate recurring workflows like daily data quality checks or weekly schema documentation refreshes.
Reconstructing distributed denial of service (DDoS) attack traffic used to mean combining data from multiple sources after the fact. AWS Shield Advanced attack flow logs change that—they capture traffic metadata during attacks so you can pinpoint sources, verify mitigations, and feed your existing analysis pipelines.
In this post, you will learn how Shield Advanced attack flow logs capture metadata during DDoS events, what each field in a flow log entry means, and how to enable and configure flow logging for your protected resources.
How DDoS attacks affect your applications
A DDoS attack floods an application with traffic, making it unavailable to users. Infrastructure-layer attacks saturate bandwidth and exhaust connection tables—you see packet loss and timeouts.
Shield Advanced is a managed DDoS protection service that detects and mitigates attacks for Amazon CloudFront distributions, Elastic Load Balancing load balancers, Amazon Route 53 hosted zones, AWS Global Accelerator standard accelerators, and Elastic IP (EIP) addresses. See the AWS Shield Advanced documentation for full coverage details. Initially, Shield Advanced will provide infrastructure-layer attack flow logs for EIP protections, with support for additional resource types to follow.
Key benefits
Flow logs help you understand attacks in several ways:
Reconstruct traffic patterns – Query logs after an attack to analyze volume, source distribution, and protocol mix without relying only on aggregate CloudWatch metrics.
Identify attack origins – The srccountry and location fields show where traffic originated and which AWS edge location it entered.
Verify mitigation behavior – The action field records what Shield did with each flow.
Logs go to Amazon S3, CloudWatch Logs, or Data Firehose. You can then query them with Amazon Athena (a serverless query service for analyzing data in Amazon S3), route them to third-party Security Information and Event Management (SIEM) platforms or build CloudWatch Logs Insights queries (an interactive log analysis feature) without deploying new infrastructure.
What attack flow logs capture
Log records capture source and destination IP addresses and ports, protocol, packet and byte counts, the action Shield Advanced took, and TCP flags. They also include the AWS ingress location where traffic entered and a two-letter country code for the traffic source when available. Logs are written at 5-minute intervals and are available during an active attack and after it concludes.
The maximum file size is 75 MB. If a file reaches that limit within the 5-minute window, the file will be closed, published, and a new file will start. Flow logs support JSON, plain text, W3C, and Parquet output formats and contain the following fields:
Field
Description
protection_arn
Amazon Resource Name (ARN) of the Shield protection
event_timestamp
Timestamp of log generation
version
Flow log version number
srcaddr
Source IP address
dstaddr
Destination IP address
srcport
Source port
dstport
Destination port
protocol
IP protocol number
packets
Packet count within the aggregation window
bytes
Byte count within the aggregation window
starttime
Aggregation window start time
endtime
Aggregation window end time
action
Action taken by Shield
location
AWS ingress location
sampling_rate
Sampling rate used during packet processing
tcp_flags
TCP flags from the packet
srccountry
Two-letter country code for the traffic source
How to configure flow logs for Shield Advanced protected resources
The following steps walk you through creating the CloudWatch Logs delivery resources that connect a Shield Advanced protection to your preferred log destination.
AWS Identity and Access Management (IAM) permissions to create CloudWatch Logs delivery resources (logs:PutDeliverySource, logs:PutDeliveryDestination, logs:CreateDelivery)
Flow logs incur standard CloudWatch Logs vended log charges, and the destination resources (S3 bucket storage, CloudWatch Logs log group storage, or Firehose data processing) incur separate charges. Review the Vended Logs entry on the CloudWatch pricing page and the pricing for your chosen destination service before enabling flow logs on high-traffic resources.
How it works
Log delivery requires three objects:
DeliverySource – Represents the Shield Advanced protection that produces the logs
DeliveryDestination – Represents where logs should be sent (Amazon S3, CloudWatch Logs, or Amazon Data Firehose)
Delivery – Connects the source to the destination
This three-object model lets you reuse destinations across multiple sources and manage delivery pipelines independently. For example, you can send logs from multiple Shield protections to the same S3 bucket by creating multiple DeliverySource objects that reference the same DeliveryDestination.
Because Shield Advanced attack flow logs use the CloudWatch Logs delivery infrastructure, you can aggregate them across accounts and Regions just like other vended logs. Deliver directly to a centralized S3 bucket with a cross-account policy, replicate CloudWatch Logs log groups using cross-account cross-Region centralization rules, or stream to a shared Firehose stream using cross-account subscriptions. Explore these options to build a unified view of DDoS attack traffic across your multi-account, multi-Region footprint.
Step 1: Create your destination resource
Choose a destination:
Option A – S3 bucket: Best for long-term storage and Athena queries. See Creating an S3 bucket.
Automatic policy creation: If your bucket has no existing resource policy and you have the s3:GetBucketPolicy and s3:PutBucketPolicy permissions, AWS automatically creates the required policy when you create the delivery in step 6. You can skip to step 3.
Manual policy update: If you need to customize the policy or your organization requires pre-approved policies, create the policy manually by following the instructions for Logs sent to Amazon S3.
Step 3: Get your protection ARN
Shield Advanced is a global service and uses the us-east-1 AWS Region for management. Run the following command to list your Shield Advanced protections.
aws shield list-protections \
  --region us-east-1
In the output, copy the ProtectionArn value for the protection you want to log.
Step 4: Create a delivery source
Run the following command to create the delivery source, replace <protection-arn> with the ProtectionArn value from step 3.
The --resource-arn is the ARN of your Shield Advanced protection—not the protected resource itself. Shield Advanced creates a separate protection object that wraps your resource, and flow logs are generated by that protection layer rather than the underlying resource.
Step 5: Create a delivery destination
Run the following command to create the delivery destination, replace <resource-arn> with the ARN of the destination resource you created in step 1.
The --delivery-destination-configuration parameter takes a JSON object with a destinationResourceArn key whose value is the ARN of your S3 bucket, log group, or Firehose stream.
In the output, copy the value of the top-level ARN field—this is the delivery destination ARN (different from the bucket ARN). You will use this in step 6.
Step 6: Create the delivery
Run the following command to connect the delivery source to the delivery destination, replace <delivery-destination-arn> with the delivery destination ARN from step 5.
Shield Advanced attack flow logs provide the visibility you need to understand and respond to DDoS attacks effectively. By integrating with your existing observability infrastructure, they deliver actionable insights without requiring new tooling or complex setup. Enable flow logs on your Shield Advanced protections today to gain immediate visibility into attack patterns and strengthen your DDoS defense posture.
Building email infrastructure with Amazon Simple Email Service (SES) involves navigating identity verification, authentication protocols, configuration sets, bounce handling, and deliverability monitoring. Developers often spend time reading documentation and iterating on API calls before getting their first email sent correctly. AI coding agents can accelerate this process, but without domain-specific context, they frequently generate code using the legacy V1 API, skip authentication setup, or miss production requirements like tenant isolation.
Today, we are releasing Amazon SES Agent Skills, an open source set of agent skills that give AI coding agents the context they need to build email integrations correctly from the start. The skills work with Kiro, Claude Code, and any agent that supports the open Agent Skills format.
What are agent skills?
Agent skills are structured context packages that teach AI agents how to use a specific service correctly. Rather than relying on general training data (which may be outdated or incomplete), a skill provides the agent with validated patterns, common mistake avoidance, and step-by-step workflows for a specific domain.
When you install the Amazon SES agent skills, your AI agent gains access to:
The correct API version and SDK client to use (SES V2, not V1)
The required order of operations (verify identity before sending, create configuration set before going to production)
Production-ready patterns including tenant isolation, bounce handling, and email validation
Common mistakes and how to avoid them
Executable example scripts in Python, Node.js, and Java
Two skills, two use cases
Amazon SES has two distinct capabilities that use different API clients:
Receiving and processing inbound email (routing, filtering, archiving, SMTP relay)
mailmanager
These are different APIs with different clients. A common mistake agents make without this context is mixing them up or using the legacy ses client for sending.
Once installed, the skill activates automatically when you ask your agent about email-related tasks.
What the agent experience looks like
After installing the aws-ses skill, ask your agent: “Help me send my first email with Amazon SES.”
Without the skill, an agent might generate code using the deprecated V1 API, skip identity verification, or omit a configuration set. With the skill, the agent follows the correct workflow:
Verifies your identity is set up (domain or email address)
Checks sandbox status and recommends simulator addresses for testing
Creates a configuration set for event tracking
Sets up a tenant for workload isolation
Generates code using the V2 API with proper error handling
Here is an example of what the agent produces for a Python quickstart:
import boto3
from botocore.exceptions import ClientError

client = boto3.client('sesv2', region_name='us-east-1')

try:
    response = client.send_email(
        FromEmailAddress='[email protected]',
        Destination={'ToAddresses': ['[email protected]']},
        Content={
            'Simple': {
                'Subject': {'Data': 'Hello from Amazon SES'},
                'Body': {'Text': {'Data': 'This email was sent using Amazon SES V2 API.'}}
            }
        },
        ConfigurationSetName='my-config-set',
        TenantName='my-tenant'
    )
    print(f"Message sent: {response['MessageId']}")
except ClientError as e:
    print(f"Send failed: {e.response['Error']['Code']} - {e.response['Error']['Message']}")
The agent knows to use sesv2 (not ses), includes a configuration set for observability, uses a tenant for isolation, and sends to a simulator address for safe testing.
What the Mail Manager skill provides
For inbound email processing, the aws-mail-manager skill teaches the agent the core pipeline architecture:
Internet → Ingress Point → Traffic Policy → Rule Set → Action
The skill ensures the agent creates resources in the correct dependency order (traffic policy and rule set before ingress point), uses the correct condition syntax (union types with exactly one key per object), and waits for the ingress point to reach ACTIVE status before recommending DNS changes.
How the skills are structured
Each skill contains:
SKILL.md — The entry point that describes capabilities, common mistakes, and when to use the skill
references/ — Task-oriented guides for specific workflows (identity verification, configuration sets, tenant setup, troubleshooting)
scripts/ or examples/ — Executable code the agent can reference or adapt
The agent loads only the context relevant to your current task. Ask about sending email and it loads the sending guides. Ask about archiving inbound email and it loads the archive reference.
Prerequisites
To use the skills, you need:
An AI coding agent that supports the Agent Skills format (Kiro, Claude Code, or compatible tools)
An AWS account with Amazon SES access
AWS credentials configured (environment variables, shared credentials file, or IAM role)
The SDK for your language: Python (boto3), Node.js (@aws-sdk/client-sesv2), or Java (software.amazon.awssdk:sesv2)
Try it today
The Amazon SES Agent Skills are available now on GitHub:
Install the skills, ask your agent to help you send your first email, and see how structured context changes the development experience. If you find issues or want to contribute, open an issue or pull request on the repository.
You can use Amazon Cognito user pools to add sign-up and sign-in functionality to your web and mobile applications. You can authenticate users directly with Amazon Cognito managed accounts using passwords, passwordless flows, or custom authentication flows, or let users federate in through external identity providers (IdP) using SAML, OpenID Connect, or social providers such as Google, Facebook, Sign in with Apple, or Login with Amazon. For consumers, identity federation means fewer passwords to remember and a smoother sign-in experience. For business-to-business (B2B) software as a service (SaaS) providers, it means your tenants’ organizations keep control of their own identities rather than managing credentials on their behalf. But federation can also introduce challenges for enterprises and application developers. What happens when your enterprise customer’s SAML provider sends hundreds of group memberships that exceed attribute size limits? Or when your ecommerce customer forgets they already have an account and tries to sign in with a different social provider, creating duplicate records?
In this blog post, I introduce the inbound federation Lambda trigger for Amazon Cognito, a new feature that gives you programmatic control over federated authentication flows. This AWS Lambda trigger intercepts the federated authentication response immediately after your external identity provider responds to Cognito, so you can transform, filter, and enrich user attributes before the user profile is created and user attributes are mapped in your user pool.
Understanding the inbound federation Lambda trigger
The inbound federation Lambda trigger is invoked after your Amazon Cognito user pool has received and verified the response from the external IdP. The request payload for the federated IdP response is then sent from Cognito to your Lambda function and you will receive the following information:
The common parameters of Amazon Cognito Lambda triggers (including userPoolId and clientId)
Which external IdP was used (for example, providerName)
The providerType (SAML, OIDC, Login with Amazon, and so on)
Attribute data from the external IdP specific to the user signing in
The specific format of this attribute data depends on the provider type, view the Inbound federation Lambda trigger parameters section in the docs to learn more. If the external IdP is a SAML provider, you will receive a JSON key-pair listing of the user’s attributes from the IdP assertion. If the external IdP is an OIDC provider (or social provider), you will receive the access token and attribute data from the /userinfo endpoint, along with an ID token if one was provided. See Figure 1 for a detailed flow of a federated sign-in with an Amazon Cognito user pool configured to use the inbound federation Lambda trigger.
Figure 1: Sequence flow of a federated login configured with the inbound federation Lambda trigger
The user begins using the application but is required to sign in first.
The managed login is rendered, and the user can select which IdP they want to sign in with. If identifiers are used with SAML or OIDC providers, the user enters their email address and Amazon Cognito looks up the domain of their provided email and routes them to the appropriate IdP.
Alternatively, the managed login can be bypassed by the client providing the identity_provider request parameter.
Amazon Cognito sends the authentication request to the appropriate IdP.
The external IdP challenges the user to sign in.
The user completes the sign-in process required by the external identity provider.
The challenge response is sent to the external IdP.
The IdP verifies that the sign-in is successful. If there are any subsequent challenges, such as multi-factor authentication (MFA), additional rounds of authentication challenges and responses take place. This is determined by the configuration and settings of the external IdP.
The external IdP sends a response to the Amazon Cognito user pool, and Cognito validates the cryptographic signature and that it hasn’t been tampered with.
Amazon Cognito sends attribute data from the IdP to the inbound federation Lambda function
Attribute data for the authenticated user and the common parameters for Amazon Cognito are available for the Lambda function to add, modify, or suppress according to your requirements.
Your added, modified, or suppressed attributes are returned to Amazon Cognito. These are attribute values that map to the user’s profile in Cognito—whether the user profile was just created or is being updated for a returning user.
Continuing the OAuth 2.0 authorization code grant, Amazon Cognito sends an authorization code to the client.
The client then calls the /token endpoint with the authorization code. Note: It’s a security best practice to use confidential clients and to use OAuth 2.0 Proof Key for Code Exchange (PKCE) extension whenever possible.
An access, ID, and refresh token is returned to the client.
The user has signed into the application. ID tokens can be used to identify who the user is (authentication), and access tokens can be used to determine what the user can do (authorization).
Common federation challenges and use cases
Federation introduces complexity that varies depending on your use case. For B2B and SaaS applications, you’re often not in control of your customers’ IdPs, including what attributes they send or how they format them. As an example, an enterprise customer will configure their SAML response to include every group a user belongs to. This could be hundreds of groups or long group identifiers, and if the group membership of the user is mapped to an Amazon Cognito attribute, this can lead to a scenario where the Cognito attribute size limit is exceeded, causing federated sign-ins to fail.
Challenges for business-to-customer (B2C) applications can differ from B2B use cases. For B2C applications, organizations shouldn’t be required to think about identity providers. The ability to sign-up and sign-in should be seamless for consumer-facing applications. Customers visiting a consumer-facing application might create an account with email and password, forget they created created it, and then later try signing in with Facebook (or other social provider). Without proper account linking in Amazon Cognito, you then have multiple user records for the same user, which could lead to fragmented purchase history and a frustrating customer experience.
Both B2B and B2C use cases might need to look up external data just prior to completing the sign-in process, such as additional roles and access for B2B users or looking up active orders for B2C users. Another example could be the need to normalize data just prior to storing it in the user profile within the Amazon Cognito user pool or even discarding personally identifiable information (PII) prior to storing it in your Cognito user pool.
With the inbound federation Lambda trigger, you can handle these B2B and B2C use cases programmatically, and do so without requiring modification of your applications or coordinating IdP-specific changes with external IdPs. In this section, I dive deeper into two common use cases: oversized group attributes, common with B2B customers, and automated account linking, common with B2C customers.
Use case 1: Filtering oversized group attributes
If you have B2B and SaaS use cases, it’s a common practice to use group membership from the IdP to determine the level of access you have within the SaaS service. This is a great way to still provide some access control back to the enterprise customers themselves. The groups can be used to represent the roles a user will have or for some form of coarse-grained authorization. However, your customers might inadvertently send a large number of groups a user is a member of, thus leading to an oversized attribute payload.
Another common scenario is where the syntax and format of group name a user belongs to can arrive in various formats across different IdPs; such as a canonical name (for example, example.com/groups/myApp-readOnly), a distinguished name (common with LDAP based systems and such as cn=myApp-readOnly,OU=groups,DC=example,DC=com), or a plain text string (such as myApp-readOnly). Instead of having downstream authorization logic to accommodate different variations of a group name, you can now normalize how groups are represented prior to storing the user’s attribute data using the inbound federation Lambda trigger.
To expand this, imagine your enterprise customer uses a SAML IdP, such as Active Directory Federation Services (AD FS), in front of Active Directory (AD). When their users authenticate, AD FS sends a groups attribute containing every AD group the user belongs to. For users in large organizations, this can be hundreds of groups, and the attribute is mapped to an Amazon Cognito attribute, this could result in a string that exceeds 2,048-character limit per attribute of Cognito. Authentication would fail in this scenario, ultimately leading to support tickets because enterprise customers would be unable to sign in. Even if certain users didn’t exceed this limit, because of a smaller number of group memberships, this would result in the collection and storing of unnecessary data in your Cognito user pool.
Previously, you would need to work with your customer’s IT department to modify their SAML configuration to filter groups at the source—a process that could take weeks and require multiple approval cycles because it involves a change to the federation configuration. Especially for SaaS customers, this isn’t a scalable approach because you could integrate with hundreds of external IdPs. With the inbound federation Lambda trigger, you can solve this by filtering the groups to only those relevant to your application and normalizing the nomenclature of these groups. The following Lambda function filters the groups attribute to include only groups relevant to your application and normalizes the names of groups.
// Configure the group prefix to filter on (e.g. "App1-", "myApp-", etc.)
// Change this to match the prefix your IdP uses for relevant group names.
const GROUP_PREFIX = process.env.GROUP_PREFIX || 'myApp-';

// The SAML attribute/claim name that contains group membership.
// Common values: "groups", "memberOf", "http://schemas.xmlsoap.org/claims/Group", etc.
const GROUP_ATTRIBUTE = process.env.GROUP_ATTRIBUTE || 'groups';

/**
 * Extracts the short group name from common IdP formats:
 *   - Plain text:       "myApp-readOnly"
 *   - Leading slash:    "/myApp-readOnly"
 *   - Canonical/URL:    "example.com/groups/myApp-readOnly"
 *   - Distinguished name (DN): "cn=myApp-readOnly,OU=groups,DC=example,DC=com"
 * Returns the last meaningful segment so all formats normalize to "myApp-readOnly".
 */

function extractGroupName(raw) {
  let name = raw.trim();

  // Some IdPs prefix group names with "/" to indicate a top level group — strip it before format detection
  if (name.startsWith('/')) {
    name = name.substring(1);
  }

  // DN format — extract the CN (common name) value
  if (/^cn=/i.test(name) || /,\s*(ou|dc)=/i.test(name)) {
    const cnMatch = name.match(/^cn=([^,]+)/i);
    return cnMatch ? cnMatch[1].trim() : name;
  }

  // URL / path format — take the last segment after the final "/"
  if (name.includes('/')) {
    const segments = name.split('/').filter(Boolean);
    return segments[segments.length - 1];
  }

  return name;
}
export const handler = async (event) => {
  try {
    console.log('Full event:', JSON.stringify(event, null, 2));
    console.log('Provider type:', event.request?.providerType);

    // Initialize the response structure
    event.response = event.response || {};

    if (event.request?.providerType?.toLowerCase() === "saml") {
      const samlResponse = event.request.attributes?.samlResponse;

      if (samlResponse) {
        console.log('Original SAML Attributes:', JSON.stringify(samlResponse, null, 2));

        // Build the attribute map — you MUST include every attribute you want Cognito to retain. Anything omitted from userAttributesToMap is dropped.
        const mappedAttributes = {};

        Object.keys(samlResponse).forEach(key => {
          if (key === GROUP_ATTRIBUTE) {
            // Parse the groups JSON string from the SAML assertion
            let groupsArray = [];
            try {
              groupsArray = JSON.parse(samlResponse[GROUP_ATTRIBUTE]);
            } catch (error) {
              console.error(`Error parsing ${GROUP_ATTRIBUTE}:`, error);
            }

            // Normalize each group name, then filter to the configured prefix
            const normalizedGroups = groupsArray.map(extractGroupName);
            const filteredGroups = normalizedGroups.filter(group =>
              group.startsWith(GROUP_PREFIX)
            );

            console.log(`Original ${GROUP_ATTRIBUTE}:`, groupsArray);
            console.log(`Normalized ${GROUP_ATTRIBUTE}:`, normalizedGroups);
            console.log(`Filtered ${GROUP_ATTRIBUTE}:`, filteredGroups);

            // Only include the groups attribute if there are matching groups
            if (filteredGroups.length > 0) {
              mappedAttributes[GROUP_ATTRIBUTE] = filteredGroups.map(group => `'${group}'`).join(', ');
            }
          } else {
            // Pass all other SAML attributes through unchanged
            mappedAttributes[key] = samlResponse[key];
          }
        });

        event.response.userAttributesToMap = mappedAttributes;
        console.log('Response to Cognito:', JSON.stringify(event.response, null, 2));
      }
    }

    // For any unhandled provider type (or missing samlResponse), this intentionally does NOT set userAttributesToMap and tells Cognito to keep all original IdP attributes unchanged (no-op).

    // To handle OIDC or social providers, add additional logic here using event.request.attributes.idToken, .userInfo, and/or .tokenResponse.

    return event;
  } catch (error) {
    console.error('Error in Lambda:', error);
    throw error;
  }
};
This approach reduces a large group list to only what is applicable to your application. Authentication succeeds, and you maintain control over your user pool’s data without depending on external configuration changes.
Use case 2: Automatic account linking
The second use case addresses a challenge that’s particularly common in B2C facing ecommerce or any consumer-facing applications; although it can also be applicable to B2B scenarios. Imagine you’re running an online retail store. A customer creates an account with their email and password to make a purchase. A few months later, they return to your site but forgot they already created an account and they see the Login with Amazon button and decide to sign in this way. Without account linking, Amazon Cognito creates a new federated user because these are technically distinct accounts, and now this customer has two separate accounts with different purchase histories and saved preferences.
This fragmentation creates a poor customer experience and complicates your business operations. You can’t see the customer’s complete purchase history, loyalty points are split across accounts, and your analytics show two distinct customers instead of one.
The inbound federation Lambda trigger can be used to solve this by automatically linking federated identities to existing local accounts based on email address. While account linking can also be implemented in a pre-sign-up Lambda trigger, the inbound federation trigger runs on every federated sign-in, not just the first, giving you access to the latest IdP attributes and the ability to apply linking logic continuously rather than only at initial account creation. If no local Amazon Cognito account exists, you can create one and then link the social provider account to it. The local account can serve as the primary identity, ensuring consistent JSON Web Tokens (JWTs) regardless of how the user signs in. The following is an example of an inbound federation Lambda trigger that can help address this use case.
import {
  CognitoIdentityProviderClient,
  ListUsersCommand,
  AdminCreateUserCommand,
  AdminLinkProviderForUserCommand
} from "@aws-sdk/client-cognito-identity-provider";

const client = new CognitoIdentityProviderClient();

export const handler = async (event) => {
  try {
    console.log('Full event:', JSON.stringify(event, null, 2));

    const { userPoolId, request, userName } = event;
    const { providerName, providerType, attributes } = request;

    // Extract email and profile attributes based on provider type
    const { email, givenName, surname } = extractAttributes(providerType, attributes);

    if (!email) {
      console.error('No email found in federated response');
      return event;
    }

    console.log(`Processing federated login for email: ${email}, provider: ${providerName} (${providerType})`);

    // Check if a local user exists with this email
    const existingUser = await findLocalUserByEmail(userPoolId, email);

    if (existingUser) {
      console.log(`Found existing local user: ${existingUser.Username}`);
      if (isAlreadyLinked(existingUser, providerName, userName)) {
        console.log(`Federated identity ${providerName}:${userName} is already linked to ${existingUser.Username}, skipping link`);
      } else {
        await linkFederatedUser(userPoolId, existingUser.Username, providerName, userName);
      }
    } else {
      console.log('No existing local user found, creating new one');
      const newUsername = await createLocalUser(userPoolId, email, givenName, surname);
      await linkFederatedUser(userPoolId, newUsername, providerName, userName);
    }

    return event;

  } catch (error) {
    console.error('Error in account linking Lambda:', error);
    throw error;
  }
};


/**
 * Check if the federated identity is already linked to the local user by inspecting the identities attribute from the ListUsers response.
 */
function isAlreadyLinked(user, providerName, federatedUsername) {
  const identities = user.Attributes?.find(a => a.Name === 'identities');
  if (!identities?.Value) return false;

  try {
    const parsed = JSON.parse(identities.Value);
    return parsed.some(id => id.providerName === providerName && id.userId === federatedUsername);
  } catch {
    return false;
  }
}

/**
 * Extract email and profile attributes based on provider type.
 * - SAML: attributes come from samlResponse
 * - OIDC/Social: attributes come from userInfo, falling back to idToken (if one exists)
 */
function extractAttributes(providerType, attributes) {
  if (providerType?.toLowerCase() === 'saml') {
    const saml = attributes?.samlResponse;
    return {
      email: saml?.email || null,
      givenName: saml?.givenName || '',
      surname: saml?.surname || ''
    };
  }

  // OIDC and social providers: prefer userInfo, fall back to idToken
  const userInfo = attributes?.userInfo;
  const idToken = attributes?.idToken;

  const source = userInfo?.email ? userInfo : idToken;

  return {
    email: source?.email || null,
    givenName: source?.given_name || '',
    surname: source?.family_name || ''
  };
}

/**
 * Find a local Cognito user (not EXTERNAL_PROVIDER) by email address.
 */
async function findLocalUserByEmail(userPoolId, email) {
  try {
    const command = new ListUsersCommand({
      UserPoolId: userPoolId,
      Filter: `email = "${email}"`
    });

    const response = await client.send(command);
    console.log('ListUsers response:', JSON.stringify(response, null, 2));

    if (!response.Users || response.Users.length === 0) {
      return null;
    }

    // Find the first user that is a true local account (not a federated-only profile)
    const localUser = response.Users.find(u => u.UserStatus !== 'EXTERNAL_PROVIDER');
    return localUser || null;
  } catch (error) {
    console.error('Error finding user by email:', error);
    throw error;
  }
}

/**
 * Create a new local Cognito user without a password.
 * With passwordless (email OTP) enabled on the user pool, the user is created with UserStatus=CONFIRMED and no FORCE_CHANGE_PASSWORD state.
 */
async function createLocalUser(userPoolId, email, givenName, surname) {
  try {
    const userAttributes = [
      { Name: 'email', Value: email }
    ];

    if (givenName) userAttributes.push({ Name: 'given_name', Value: givenName });
    if (surname) userAttributes.push({ Name: 'family_name', Value: surname });

    const command = new AdminCreateUserCommand({
      UserPoolId: userPoolId,
      Username: email,
      UserAttributes: userAttributes,
      MessageAction: 'SUPPRESS'
    });

    const response = await client.send(command);
    console.log(`Created local user: ${email}`, JSON.stringify(response, null, 2));

    return email;
  } catch (error) {
    console.error('Error creating local user:', error);
    throw error;
  }
}

/**
 * Link a federated user identity to a local Cognito user.
 * The local user becomes the primary profile — all future JWTs will represent this local user regardless of sign-in method.
 */
async function linkFederatedUser(userPoolId, localUsername, providerName, federatedUsername) {
  try {
    const command = new AdminLinkProviderForUserCommand({
      UserPoolId: userPoolId,
      DestinationUser: {
        ProviderName: 'Cognito',
        ProviderAttributeValue: localUsername
      },
      SourceUser: {
        ProviderName: providerName,
        ProviderAttributeName: 'Cognito_Subject',
        ProviderAttributeValue: federatedUsername
      }
    });

    const response = await client.send(command);
    console.log(`Linked federated user ${federatedUsername} to local user ${localUsername}`);
    console.log('Link response:', JSON.stringify(response, null, 2));

    return response;
  } catch (error) {
    if (error.name === 'AliasExistsException' || error.message?.includes('already linked')) {
      console.log(`User already linked: ${error.message}`);
      return;
    }
    console.error('Error linking federated user:', error);
    throw error;
  }
}
Every federated sign-in will invoke the inbound federation Lambda trigger, and the logic is straightforward. When a user authenticates with an external identity provider, the trigger extracts their email from the federated response and searches the user pool for a local Cognito account with that same email. If one exists—such as if the user originally signed up with email and password—the Lambda function links the federated identity to that existing local account. If no local account exists, the trigger creates one on the fly as a passwordless account (confirmed, suppressing any emails, and ready for passwordless email one-time passcode (OTP) sign-in), then links the federated identity to it. In both cases, the local account is set as the primary profile. This means the user’s JWTs always carry the same sub-claim regardless of how they sign in—directly, or through Google, Facebook, or SAML—your application sees one consistent identity. The preceding Lambda trigger is also smart enough to check whether a linked account already exists before making the call, so returning users who’ve already been linked don’t generate unnecessary API calls. And because the local account supports passwordless authentication, a user who first arrived through federation can later sign in directly with an emailed OTP—or even add a password later through your applications account settings. The local account is always the anchor.
Best practices
As you implement these patterns, keep a few best practices in mind. Your Lambda function must be completed within 5 seconds, so optimize for speed to help ensure the federated sign-in process is able to successfully complete. If you’re making external calls within the inbound federation Lambda function, like Amazon DynamoDB queries or API requests, implement caching where possible. Handle errors gracefully—if your Lambda function throws an exception or an error, authentication could fail for the user. Consider logging the error and returning the original event back to Amazon Cognito rather than failing authentication for a legitimate user attempting to sign in. Here are some additional best practices for working with Lambda functions.
For the account linking use case, automatic linking relies on matching the email from the federated identity to a local account. However, there are scenarios where this match won’t exist. For example, Apple’s Hide My Email feature generates a unique alias for each app, so the federated email won’t match any existing local account. This is an effective privacy feature but it also blocks the ability to automatically link accounts. In cases like these, your application will need to implement a user-initiated account linking flow, such as prompting the user to verify ownership of both email addresses before calling the AdminLinkProviderForUser API to complete the link.
Monitor your Lambda function performance using Amazon CloudWatch metrics. Set up alarms for errors, timeouts, and throttling so you can respond quickly if issues arise. I also recommend capturing sample event payloads from a CloudWatch log group during your initial development and deployment—these will be valuable for local testing and debugging which can lead to quicker resolution if issues arise in your production environment. This is especially important as different IdPs (namely SAML and OIDC providers) may respond with varying attribute and value syntaxes. Consider implementing CloudWatch alarms to alert your security and operational teams if authentication failures spike, which could indicate an attempted attack, misconfiguration, or provide insight into further optimization of your inbound federation Lambda trigger.
Conclusion
In this post, you learned about the new inbound federation Lambda trigger for Amazon Cognito and how it can solve various use cases. You walked through two common federation challenges and reviewed some sample code to help resolve those challenges. For B2B and SaaS applications, the inbound federation Lambda trigger gives you control when dealing with oversized attributes from external identity providers (such as group membership) without requiring coordination with enterprise IT teams. For B2C and consumer-facing applications, it enables seamless account linking across multiple authentication methods, creating a unified customer experience.
The new Lambda trigger works with SAML, OIDC, and supported social providers, and is available now in AWS Regions where Amazon Cognito is available. To learn more about the new Lambda trigger and others, see the Amazon Cognito Developer Guide.
What federation challenges are you facing in your applications? I’d love to hear about your use cases in the comments below and over at AWS re:Post.
Maintaining visibility into your data catalog’s health requires more than ad-hoc queries. Data stewards and compliance teams need automated dashboards that surface governance metrics and alert them when issues arise. These issues include undocumented assets, missing ownership, and stale metadata.
In a previous post, we showed you how to query Amazon SageMaker Catalog metadata using SQL by using the metadata export feature. This post builds on that foundation by demonstrating how to create governance dashboards with Amazon Quick.
Amazon Quick is an agentic AI-powered digital workspace that provides integrated analytics, automation, and research capabilities. With Amazon Quick Sight, a component of Amazon Quick, you can create interactive dashboards and visualizations with automatic chart suggestions and machine learning (ML) insights.
We walk through how to connect Amazon Quick Sight to your Amazon SageMaker Catalog metadata and build governance dashboards using natural language prompts.
Solution overview
This solution extends the metadata export architecture by adding a visualization layer:
Amazon SageMaker Catalog exports asset metadata daily to Amazon Simple Storage Service (Amazon S3) Tables
Amazon Athena queries the metadata using standard SQL
Amazon Quick Sight connects to Athena for interactive dashboards
Amazon Quick uses natural language to build visualizations
Both the Amazon Quick Sight service role and your Amazon Quick Sight admin user need AWS Lake Formation permissions on the S3 Tables catalog. First, find your Amazon Quick Sight admin user ARN by running this AWS Command Line Interface (AWS CLI) command:
Enter your Amazon Quick Sight admin user ARN (from the preceding command).
Under LF-Tags or catalog resources, choose Named Data Catalog resources.
For Catalogs, choose the S3 Tables catalog: ACCOUNT_ID:s3tablescatalog/aws-sagemaker-catalog.
For Databases, choose asset_metadata.
Under Tables, choose asset.
For Table permissions, choose Select and Describe.
Select Grant.
Figure 2 – Grant access to Amazon SageMaker Catalog resources
Repeat steps 1–9 for the Amazon Quick Sight service role, but in step 2 choose IAM users and roles instead.
When choosing the catalog in the Lake Formation console, you must choose the full S3 Tables catalog identifier (ACCOUNT_ID:s3tablescatalog/aws-sagemaker-catalog) to see the asset_metadata database.
Create an Amazon Quick Sight dataset.
Access S3 Tables data by creating a Quick Sight dataset using an Amazon Athena data source and the custom SQL option. An S3 Tables data source is also available but requires additional permissions. See Introducing new data source with S3 Tables in Amazon Quick for using S3 Tables as an Amazon Quick data source.
Open Amazon Quick Sight in the AWS Management Console.
Select Analyses and Create analysis.
Figure 3 – Create Amazon Quick Sight analysis
Choose Create dataset and Create data source.
Figure 4 – Create dataset
Select Amazon Athena as the data source and select Next.
Enter a Data source name (for example, “SageMaker Catalog Metadata”) and choose Create data source.
Figure 5 – Create data source
Select Use custom SQL and enter a custom SQL query that references the S3 Tables catalog using the full three-part name.
Figure 6 – Use custom SQL
Figure 7 – Enter custom SQL
SELECT * FROM "s3tablescatalog/aws-sagemaker-catalog".asset_metadata.asset
Select Confirm query.
Choose Directly query your data (SPICE import may fail with S3 Tables catalogs)
Figure 8 – Directly query your data
Choose Visualize and Create to start building your dashboard.
Create visualizations with Amazon Quick.
With Amazon Quick, you can build governance dashboards using natural language prompts. This removes the need for manual field configuration. This approach is faster and more intuitive than traditional dashboard building.The Amazon Quick Sight user must have AdminPro or AuthorPro subscription (the Build feature isn’t available for Reader users).Start building your dashboard with the following steps:
Select Build in the top toolbar to open the natural language builder.
Figure 9 – Amazon Quick build dashboard
You will see a text box where you can describe the visualization that you want to create.
Create each visualization using natural language. For each of the six recommended visualizations, enter the corresponding natural language prompt, select Build, then choose ADD TO ANALYSIS.
Figure 11 – Add to analysis
Visualization 1: Asset inventory by type
Show count of asset_id by resource_type_enum as a pie chart
After the pie chart is created, choose ADD TO ANALYSIS.
Visualization 2: Documentation completeness
Show count of asset_id where business_description is not null asa KPI
After the KPI is created, choose ADD TO ANALYSIS.
Visualization 3: Monthly registration trends
Show count of asset_id by asset_created_time month as a line chart
After the line chart is created, choose ADD TO ANALYSIS.
Visualization 4: Asset count by account
Show count of asset_id by account_id as a bar chart
After the bar chart is created, choose ADD TO ANALYSIS.
Visualization 5: Namespace distribution
Show count of asset_id by namespace as a treemap
After the treemap is created, choose ADD TO ANALYSIS.
Visualization 6: Resource type by namespace
Show count of asset_id by resource_type_enum and namespace as a heat map
Choose ADD TO ANALYSIS
Arrange and publish your governance dashboard with the following steps:
Delete any empty or unwanted visualizations by choosing the three dots menu and choosing Delete.
Arrange visualizations by dragging them into your preferred layout.
Resize visualizations to emphasize key metrics.
Add titles to each visualization for clarity.
Choose PUBLISH in the top right corner.
Enter a dashboard name: “SageMaker Catalog Governance Dashboard”.
After you publish, you can ask questions about your governance data:
On the dashboard, choose Analyze this dashboardin a Scenario in the top center.
In the Data to Insights panel, enter natural language questions such as:
“Which resource types have the lowest documentation rates?”
“How many assets were registered last month compared to this month?”
“What percentage of assets lack ownership information?”
Choose Submit to generate AI-powered insights.
Amazon Quick analyzes your data and provides insights with supporting visualizations.
Generate executive summaries
Create automated governance reports for data stewards and compliance teams:
Choose the Amazon Quick logo in the top left to return to the home page
Select Dashboards from the left panel
Choose your “SageMaker Catalog Governance Dashboard”
Choose the Create dropdown menu in the top right
Select Executive Summary
Amazon Quick will automatically generate a summary with key governance insights, including Total asset counts and growth trends, Documentation completeness metrics, Ownership coverage statistics, and Classification distribution analysis.
Create governance stories.
Build governance reports that combine multiple dashboards:
From the Create dropdown, select Story.
Enter a prompt: “Write a summary of catalog governance metrics and data quality trends”.
Choose Add to select dashboards to include in the report.
Choose Build (this might take a few minutes to complete).
Amazon Quick will generate a narrative report combining your visualizations with AI-generated insights. Share the reports with leadership or compliance teams.
Governance dashboards contain metadata such as ownership and classification details. Restrict access to users who need it. In the Amazon Quick Sight console, open the dashboard, choose Share, and grant access to named users or a dedicated Quick Sight group (for example, data-stewards) instead of selecting Everyone in this account. Review the dashboard’s permissions periodically and remove entries that are no longer needed.
Cleaning up
To avoid ongoing charges, clean up the resources created in this walkthrough. Delete Amazon Quick Sight resources including the dashboard, analyses, and dataset.
Conclusion
In this post, you connected Amazon Quick Sight to your Amazon SageMaker Catalog metadata export, built governance dashboards using the Amazon Quick natural language prompts. This approach gives data stewards and compliance teams visibility into catalog health through six key visualizations covering asset inventory, documentation completeness, registration trends, account distribution, classification coverage, and stale asset detection.
When you develop SQL against Amazon Redshift and Amazon Athena, you spend time finding the right tables across hundreds of databases, writing complex joins and aggregations, debugging failed queries without context from previous attempts, and re-specifying filters for every new question. Amazon SageMaker Data Agent in Query Editor takes a different approach. You describe what you need in natural language, and the Data Agent generates the SQL. It references your actual tables through AWS Glue Data Catalog, proposes step-by-step plans for complex questions, retains context across your session, and offers one-click error recovery with Fix with AI. In this post, you learn how to use Data Agent in Query Editor to explore data, build multi-step analyses, recover from errors, and summarize results using a public education dataset.
Solution overview
You can go from a natural language question to executable SQL in seconds. Data Agent in Query Editor provides a conversational interface with direct access to your AWS data environment, so you spend less time on query mechanics and more time on analysis. Data Agent in Query Editor focuses specifically on SQL development against Amazon Redshift and Amazon Athena. (For Python, SQL, and PySpark across broader analytical and machine learning (ML) workloads, use Data Agent in notebooks.)
Data Agent provides four key capabilities:
Catalog-aware SQL generation. You don’t need to browse catalog structures or memorize schema details. Data Agent reads your table metadata directly.
Querybook and session context. You build on previous work. Data Agent uses context from your earlier queries and results.
Step-by-step planning. You review and approve a structured plan before Data Agent generates SQL.
Fix with AI. You recover from failed queries with one click.
Data Agent integrates with AWS Glue Data Catalog and reads your actual table names, column types, descriptions, and relationships, so generated SQL references your real tables. Each follow-up question builds on your current Query Editor session—the SQL cells in your querybook, the active connection, your selected cell, and execution results from previously run cells. For complex requests, Data Agent produces a structured plan that specifies which data to retrieve, how to aggregate it, and what filters to apply. You review and approve each step before Data Agent proceeds. When a query fails, choose Fix with AI to get a corrected query based on the error and the failed cell’s context.
[Figure 1: The Query Editor Fix with AI panel, showing a corrected SQL query ready for your review.]
Walkthrough: Education data analysis
In this section, you use Data Agent in Query Editor to analyze California schools data and identify where SAT improvement investment has the most impact. The walkthrough covers four tasks:
Explore available data.
Build a multi-step analysis plan.
Summarize insights from your queries.
Recover from a failed query.
The same workflow applies to your own data, whether you are analyzing sales figures, operational metrics, or financial records.
The California schools dataset contains SAT score results, school demographic information, and county-level data for public schools across California. The dataset includes tables that organize SAT scores by subject (reading, writing, math), school details (name, address, county, district), and enrollment figures. After you upload the data into your project database, you directly access the tables from Query Editor through your Amazon Athena or Amazon Redshift Lakehouse connection.
Prerequisites
To complete this walkthrough, you need intermediate SQL knowledge and basic familiarity with the AWS Management Console. You don’t need prior AWS Glue experience, but familiarity with data catalogs (centralized metadata repositories) helps.
You can choose one of two setup paths:
Quick start (5 minutes). SageMaker Unified Studio provides a sample database (sagemaker_sample_db) with pre-loaded data. To explore it, choose Data in the navigation pane, expand AwsDataCatalog, and select sagemaker_sample_db.
Full setup (30–45 minutes). Upload the California schools dataset into your project’s Lakehouse database. This dataset is publicly available from the California Department of Education. Download the SAT scores, school information, and county-level data files, then upload them through the SageMaker Unified Studio UI. In your project, go to Build, choose Query editor, right-click your project database in the Data explorer, and choose Create table. Drag and drop each CSV file to create the tables. SageMaker Unified Studio stores the data in the project-managed Amazon Simple Storage Service (Amazon S3) location, registers it in AWS Glue Data Catalog, and applies AWS Lake Formation governance automatically.
Running queries against Amazon Athena or Amazon Redshift might incur costs. For pricing details, refer to Amazon Athena pricing and Amazon Redshift pricing. For detailed setup instructions, refer to AWS Identity and Access Management (IAM)-based domains and projects. Before starting the walkthrough, you must have a SageMaker Unified Studio IAM-based domain with a project using the SQL analytics or All Capabilities project profile. The project automatically provisions an AWS Glue database, the required IAM role, and Athena or Redshift Lakehouse connections.
[Figure 2: The Data Explorer panel in Query Editor, showing the california_schools_db and sagemaker_sample_db tables.]
Explore available data. To start, enter the following prompt in the Data Agent panel:
Query my SAT scores from my california_schools_db
Data Agent searches AWS Glue Data Catalog, locates the relevant tables, and generates an initial exploratory query that retrieves SAT score records. It adds a SQL cell directly to your querybook.
Review the generated SQL in the comparison view, which highlights the proposed code.
Choose Accept, Reject, or Accept and run.
After you run the cell, the results appear inline, giving you a view of the data (column names, score ranges, and the number of records) before you write SQL.
[Figure 3: Data Agent returns an exploratory query for the california_schools_db tables, ready for your review.]
[Figure 4: The SQL query results appear beneath the cell after you choose Accept and run.]
Build a multi-step analysis plan. With the data explored, enter a more complex analytical question:
Identify which subjects need investment to improve SAT scores in the lowest-performing counties. Include school-level details with addresses.
Data Agent proposes a step-by-step plan before generating SQL. For this request, Data Agent breaks the question into three steps:
Aggregate SAT scores by county and subject to find performance patterns.
Filter to counties with a sufficient number of schools and rank the lowest performers.
Join school address data to produce a final detailed list.
Review the plan in the Data Agent panel and choose Run step-by-step to proceed.
[Figure 5: Data Agent proposes a multi-step plan with options to Cancel plan or Run step-by-step.]
Data Agent generates SQL for each step and adds it as a separate querybook cell. Review each cell’s SQL in the comparison view, then choose Accept and run to execute it. The results from each step are visible inline, so you can verify the intermediate output (county-level aggregations, the filtered ranking, and the final school list) before moving to the next step. When the steps are complete, your querybook contains the full analytical progression from raw scores to a detailed investment list.
[Figure 6: Each plan step produces a querybook cell that you can review and run independently.]
Summarize insights from your queries. After running the analysis, enter the following prompt:
Summarize the insights from my queries
Data Agent has context on your querybook, including the SQL and the query results from each cell. It generates a natural language summary: which counties are underperforming, which subjects (reading, writing, or math) need the most attention in each county, and how many schools appear on the investment list. This summary provides a starting point for a report or presentation.
[Figure 7: Data Agent summarizes insights from the accumulated query results in the querybook.]
Recover from a failed query. During the analysis, a generated query might produce an error, for example, referencing a column name that doesn’t match the schema or a join condition that returns unexpected results. When a cell fails, Query Editor displays the error message and a Fix with AI option.
Choose Fix with AI, and Data Agent reads the error in the context of the failed cell, then generates corrected SQL and updates the querybook cell. Run the corrected cell to verify the fix.
[Figure 8: After you choose Fix with AI, Data Agent is prompted to generate a corrected query for the failed cell.]
[Figure 9: Data Agent returns corrected SQL for you to review.]
Security and governance
Data Agent operates within your AWS environment and only accesses data that your IAM policies explicitly permit. Your existing IAM access controls and AWS Lake Formation permissions determine what data Data Agent can reach. To use Data Agent, your project role must have permissions to invoke specific Amazon DataZone APIs. For more information, refer to Actions, resources, and condition keys for Amazon DataZone.
Data Agent includes content filtering that prevents it from responding to off-topic requests, requests to reveal its system prompt, and requests for internal technical implementation details. Data Agent is restricted to AWS-related topics and English-language output.
Amazon SageMaker stores your natural language prompts and generated SQL in the AWS Region where you created your SageMaker Unified Studio domain. Data Agent doesn’t store your data, querybook context, or catalog metadata.
The walkthrough creates querybook cells in your Query Editor session but doesn’t provision standalone infrastructure. To remove the generated SQL cells, delete them from your querybook or delete the querybook itself.
If you uploaded the California schools dataset specifically for this walkthrough, remove the following resources to avoid ongoing charges:
SageMaker Unified Studio domain. If you created a domain solely for this walkthrough, delete it to stop incurring charges. Refer to the SageMaker Unified Studio administration guide for deletion steps.
Uploaded tables. In the Data explorer, right-click each table you created and choose Delete table to remove the data from your project database and the underlying S3 storage.
Amazon Athena query results. Amazon Athena stores query results in an S3 output location. Delete the query result files from that bucket, or delete the bucket if you created it solely for this walkthrough.
Amazon CloudWatch logs. If Amazon Athena queries generated CloudWatch log groups, delete those log groups to avoid storage charges.
Conclusion
Data Agent in Query Editor brings conversational, catalog-aware SQL development to your Amazon Redshift and Amazon Athena workloads. In this post, you explored unfamiliar data, built a multi-step investment analysis, recovered from query errors, and summarized findings through natural language prompts.
Data Agent works within your existing IAM and AWS Lake Formation security controls, keeps your data within your AWS environment, and retains context across your analytical workflow so each question builds on the last.
Get started with these next steps:
Run your first prompt. Open Query Editor in your SageMaker Unified Studio domain and enter Show me the top 10 tables in my catalog with the most columns. For setup, refer to the SageMaker Unified Studio getting started guide.
Add descriptions to your AWS Glue Data Catalog. Table descriptions and column-level business metadata improve the quality of generated SQL. For best practices, refer to Populating the AWS Glue Data Catalog.
Try a multi-step analysis. Enter Which product categories had declining revenue quarter-over-quarter, and which regions drove the decline? and review Data Agent’s plan step by step.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
 Figure 1: VPC Lattice resource configuration showing the custom domain name field and resource definition populated with the Amazon MQ broker endpoint.
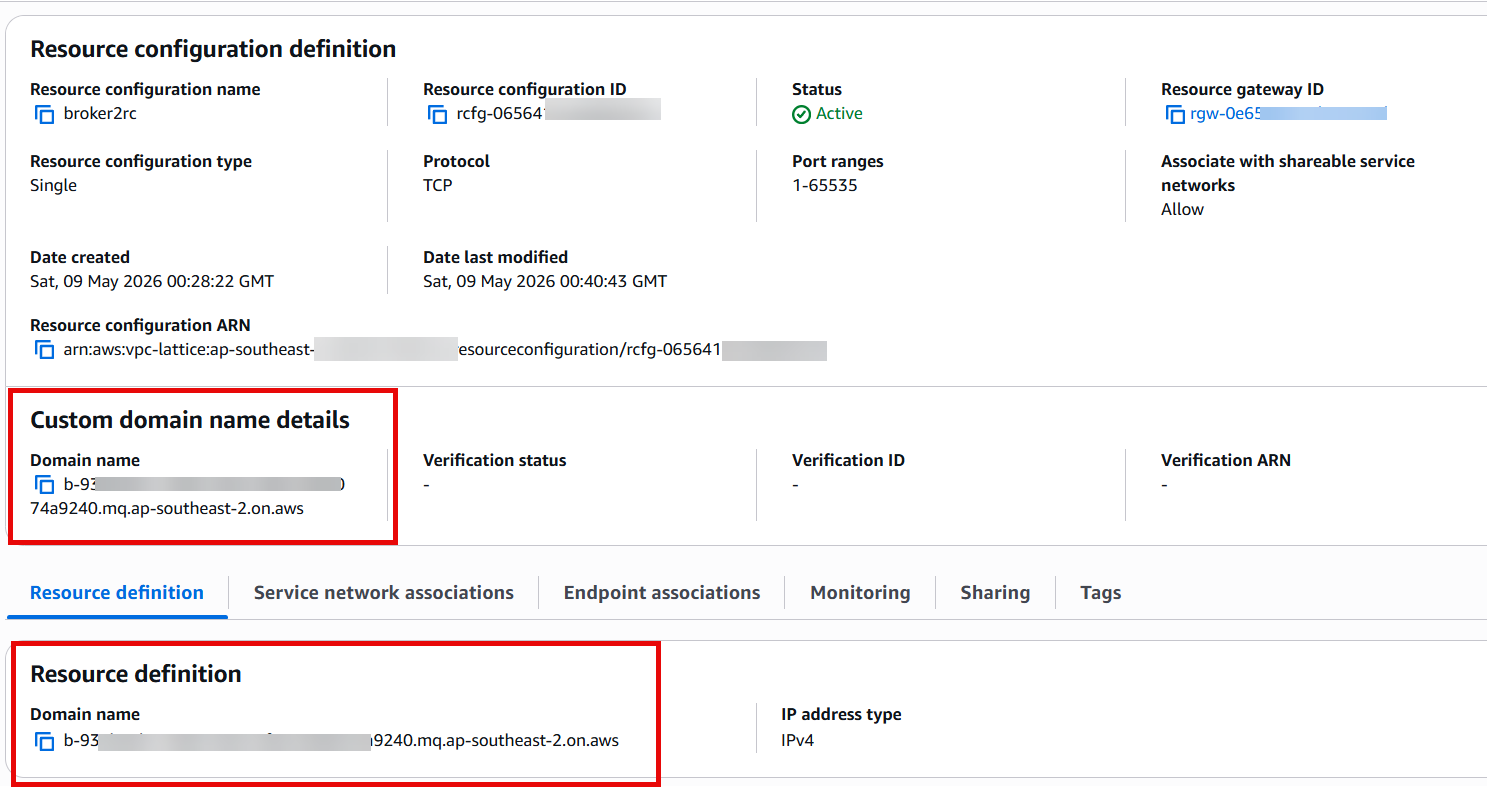 Figure 1: VPC Lattice resource configuration showing the custom domain name field and resource definition populated with the Amazon MQ broker endpoint.
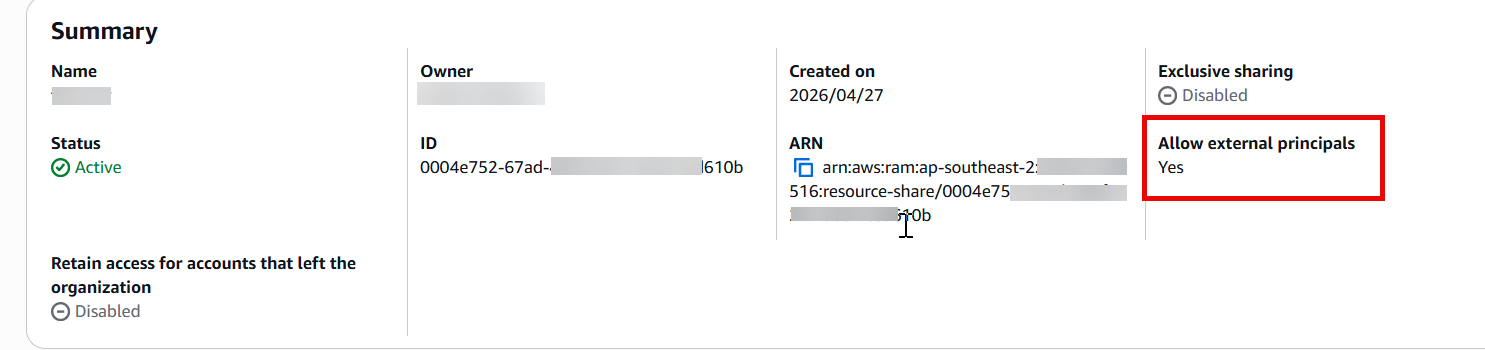 Figure 2: RAM resource share configuration with the Allow external principals option selected.
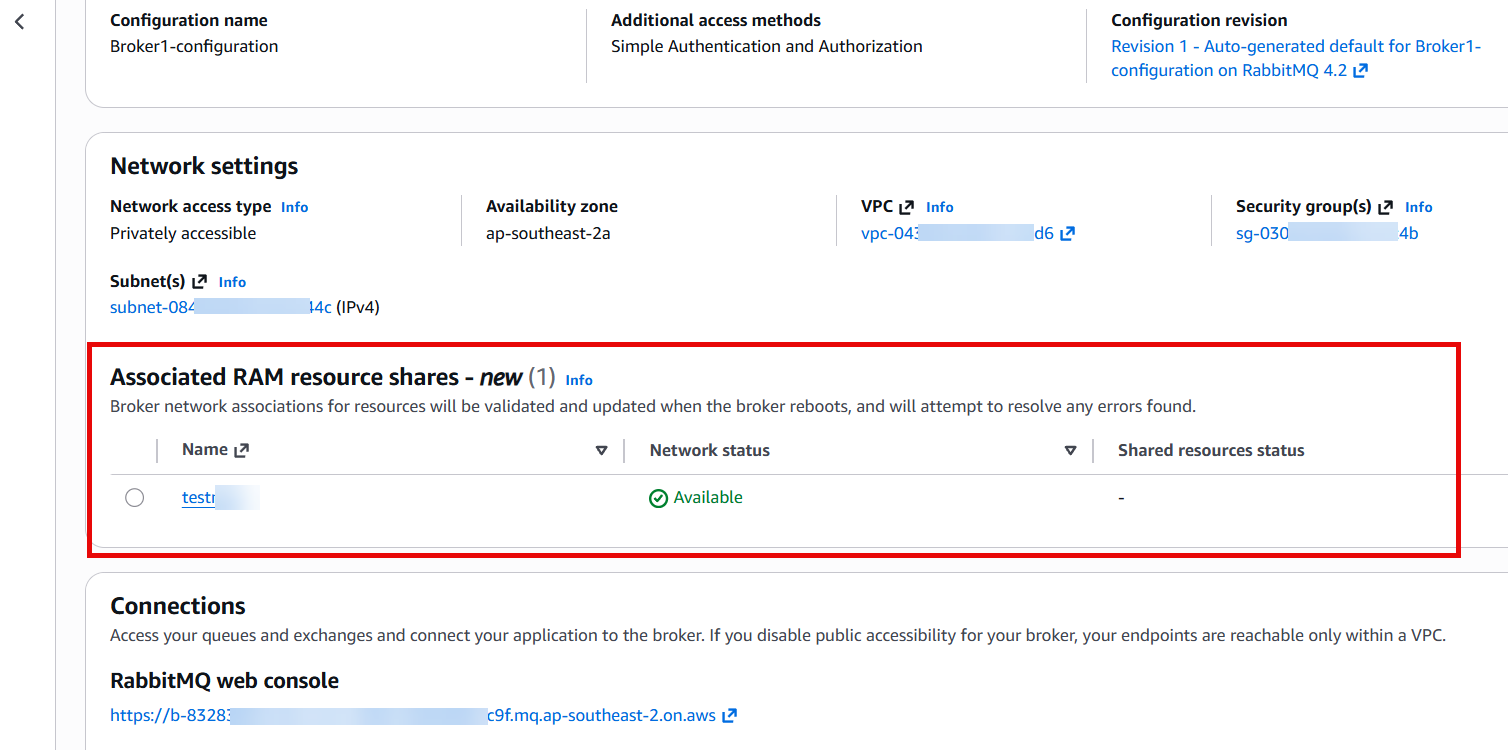
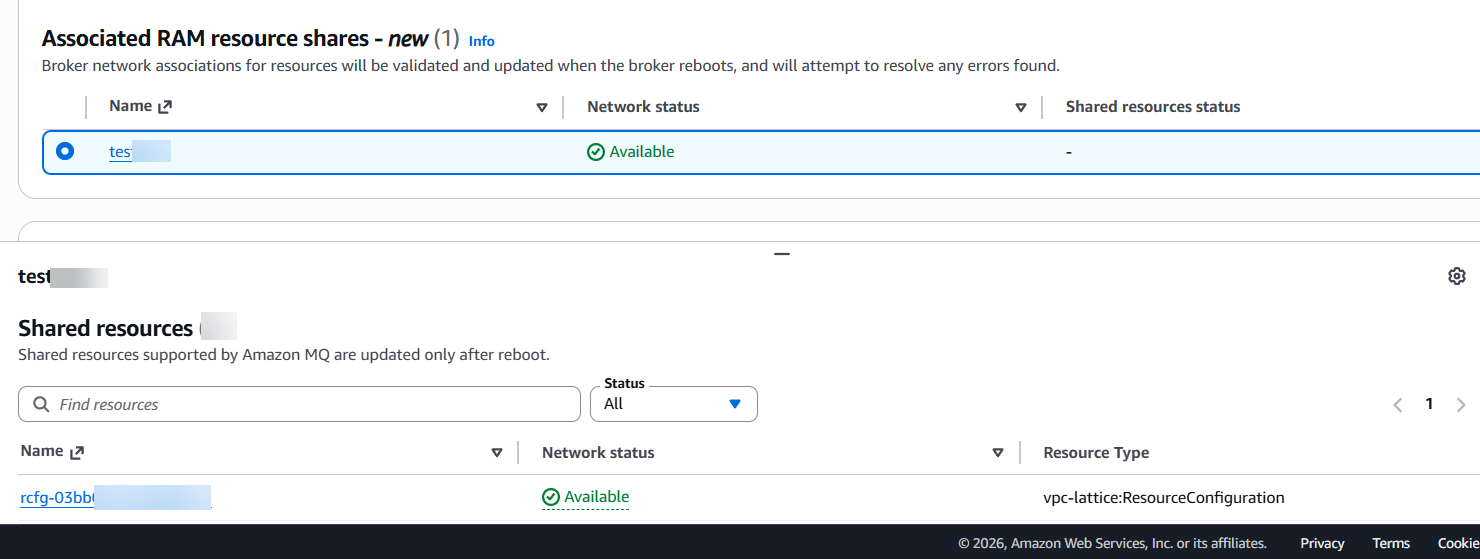
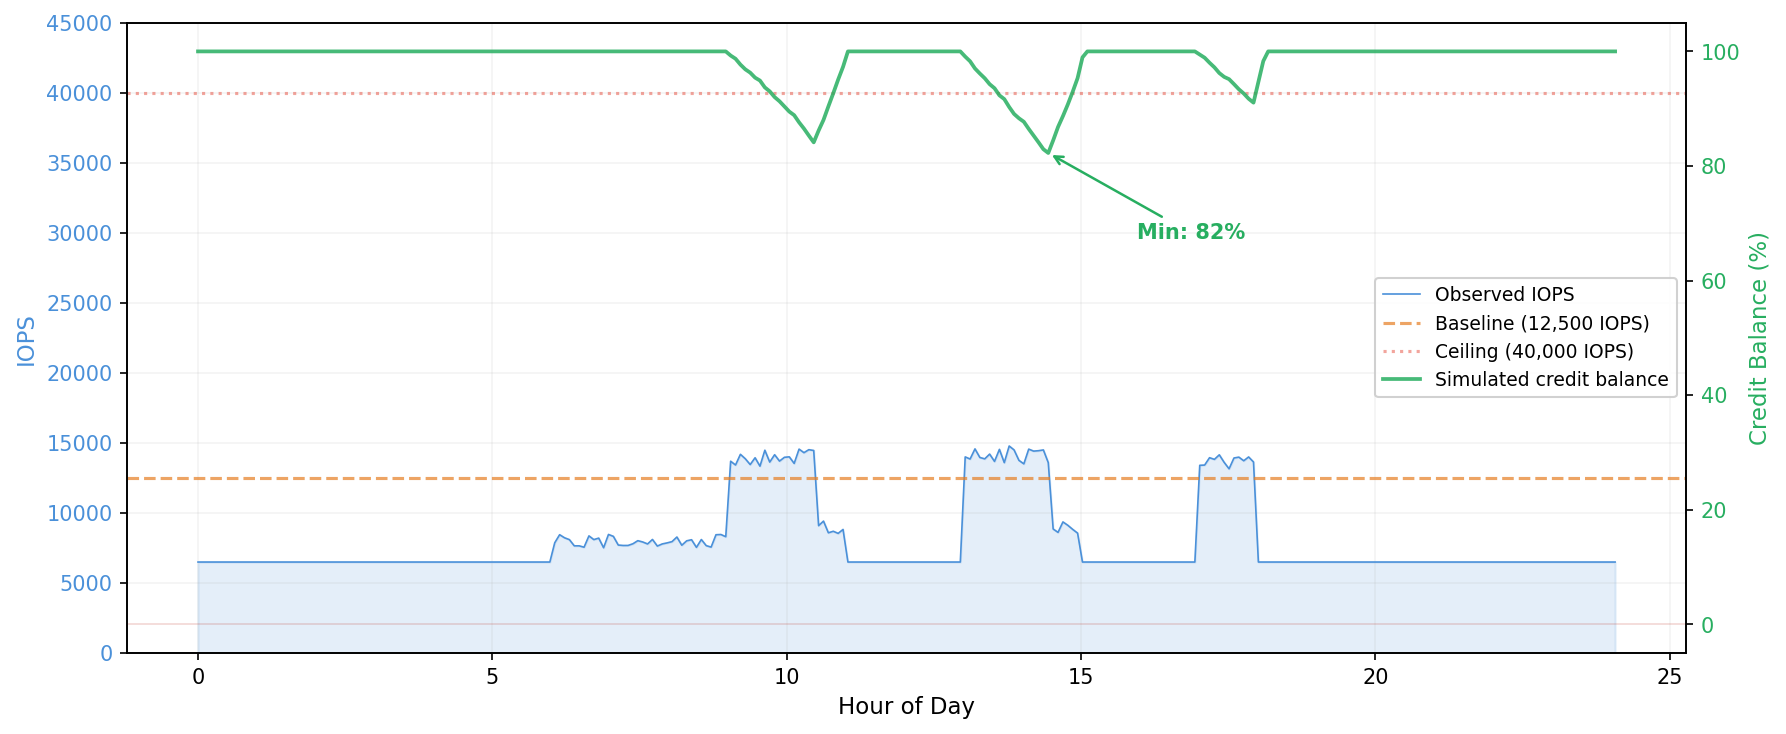
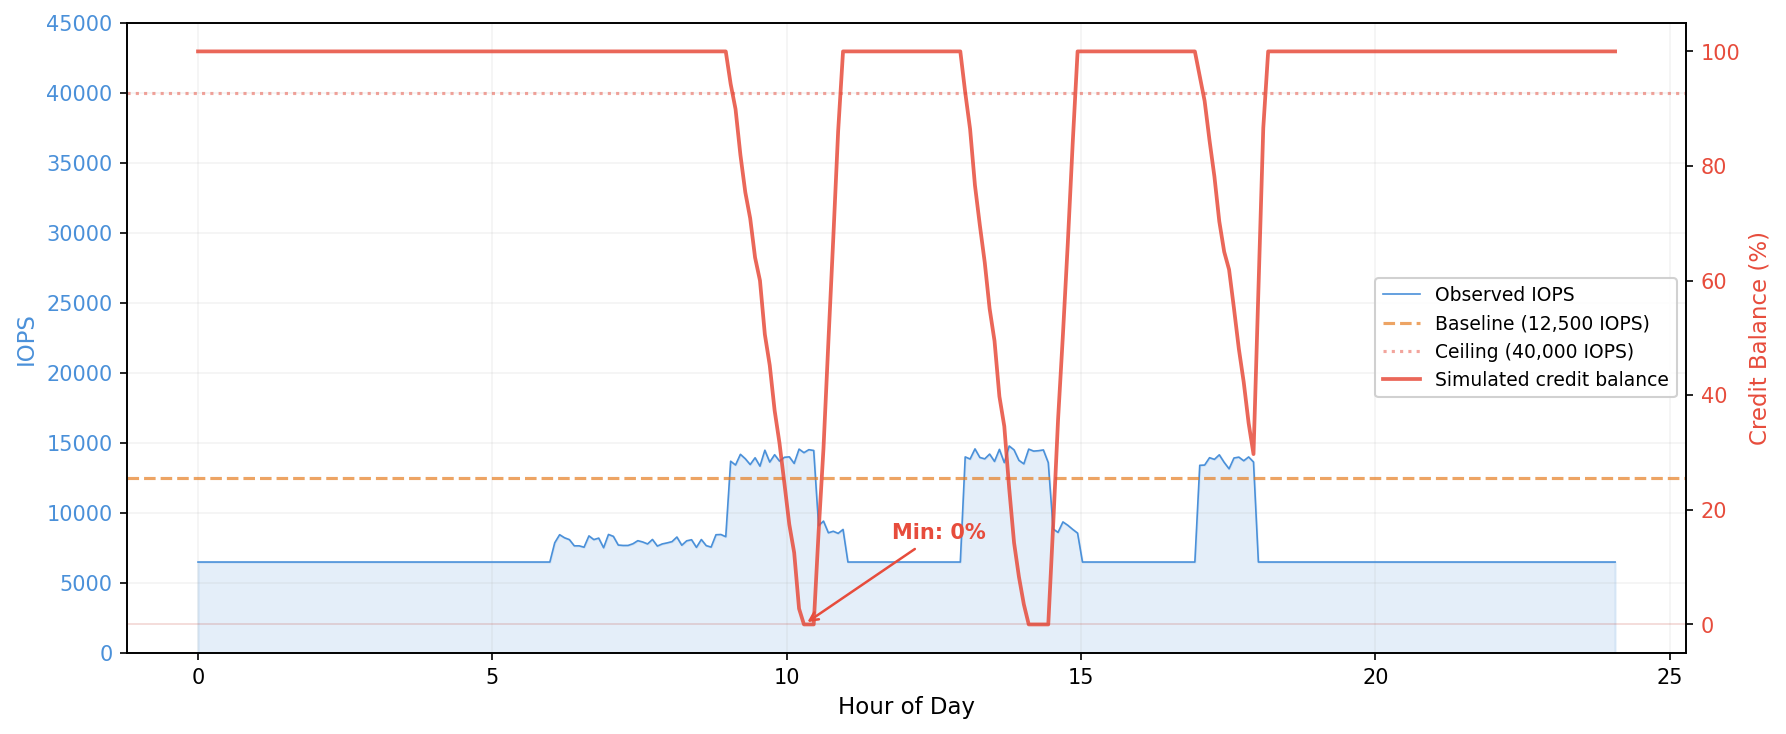
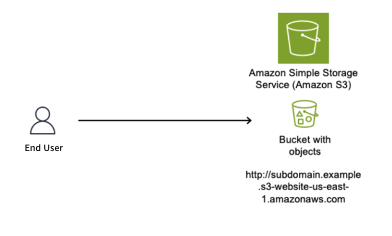
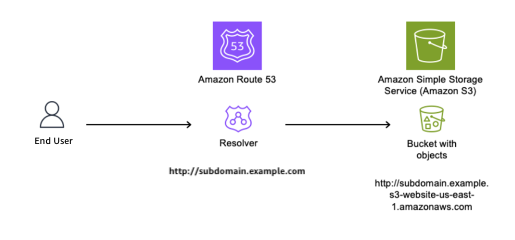
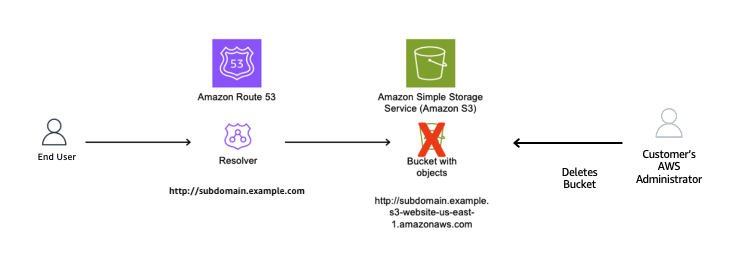
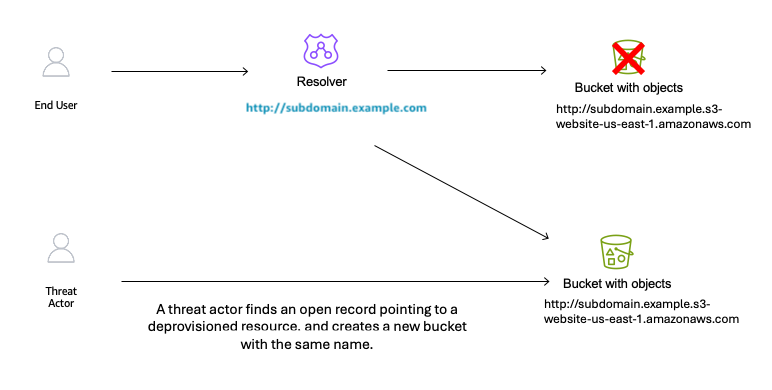
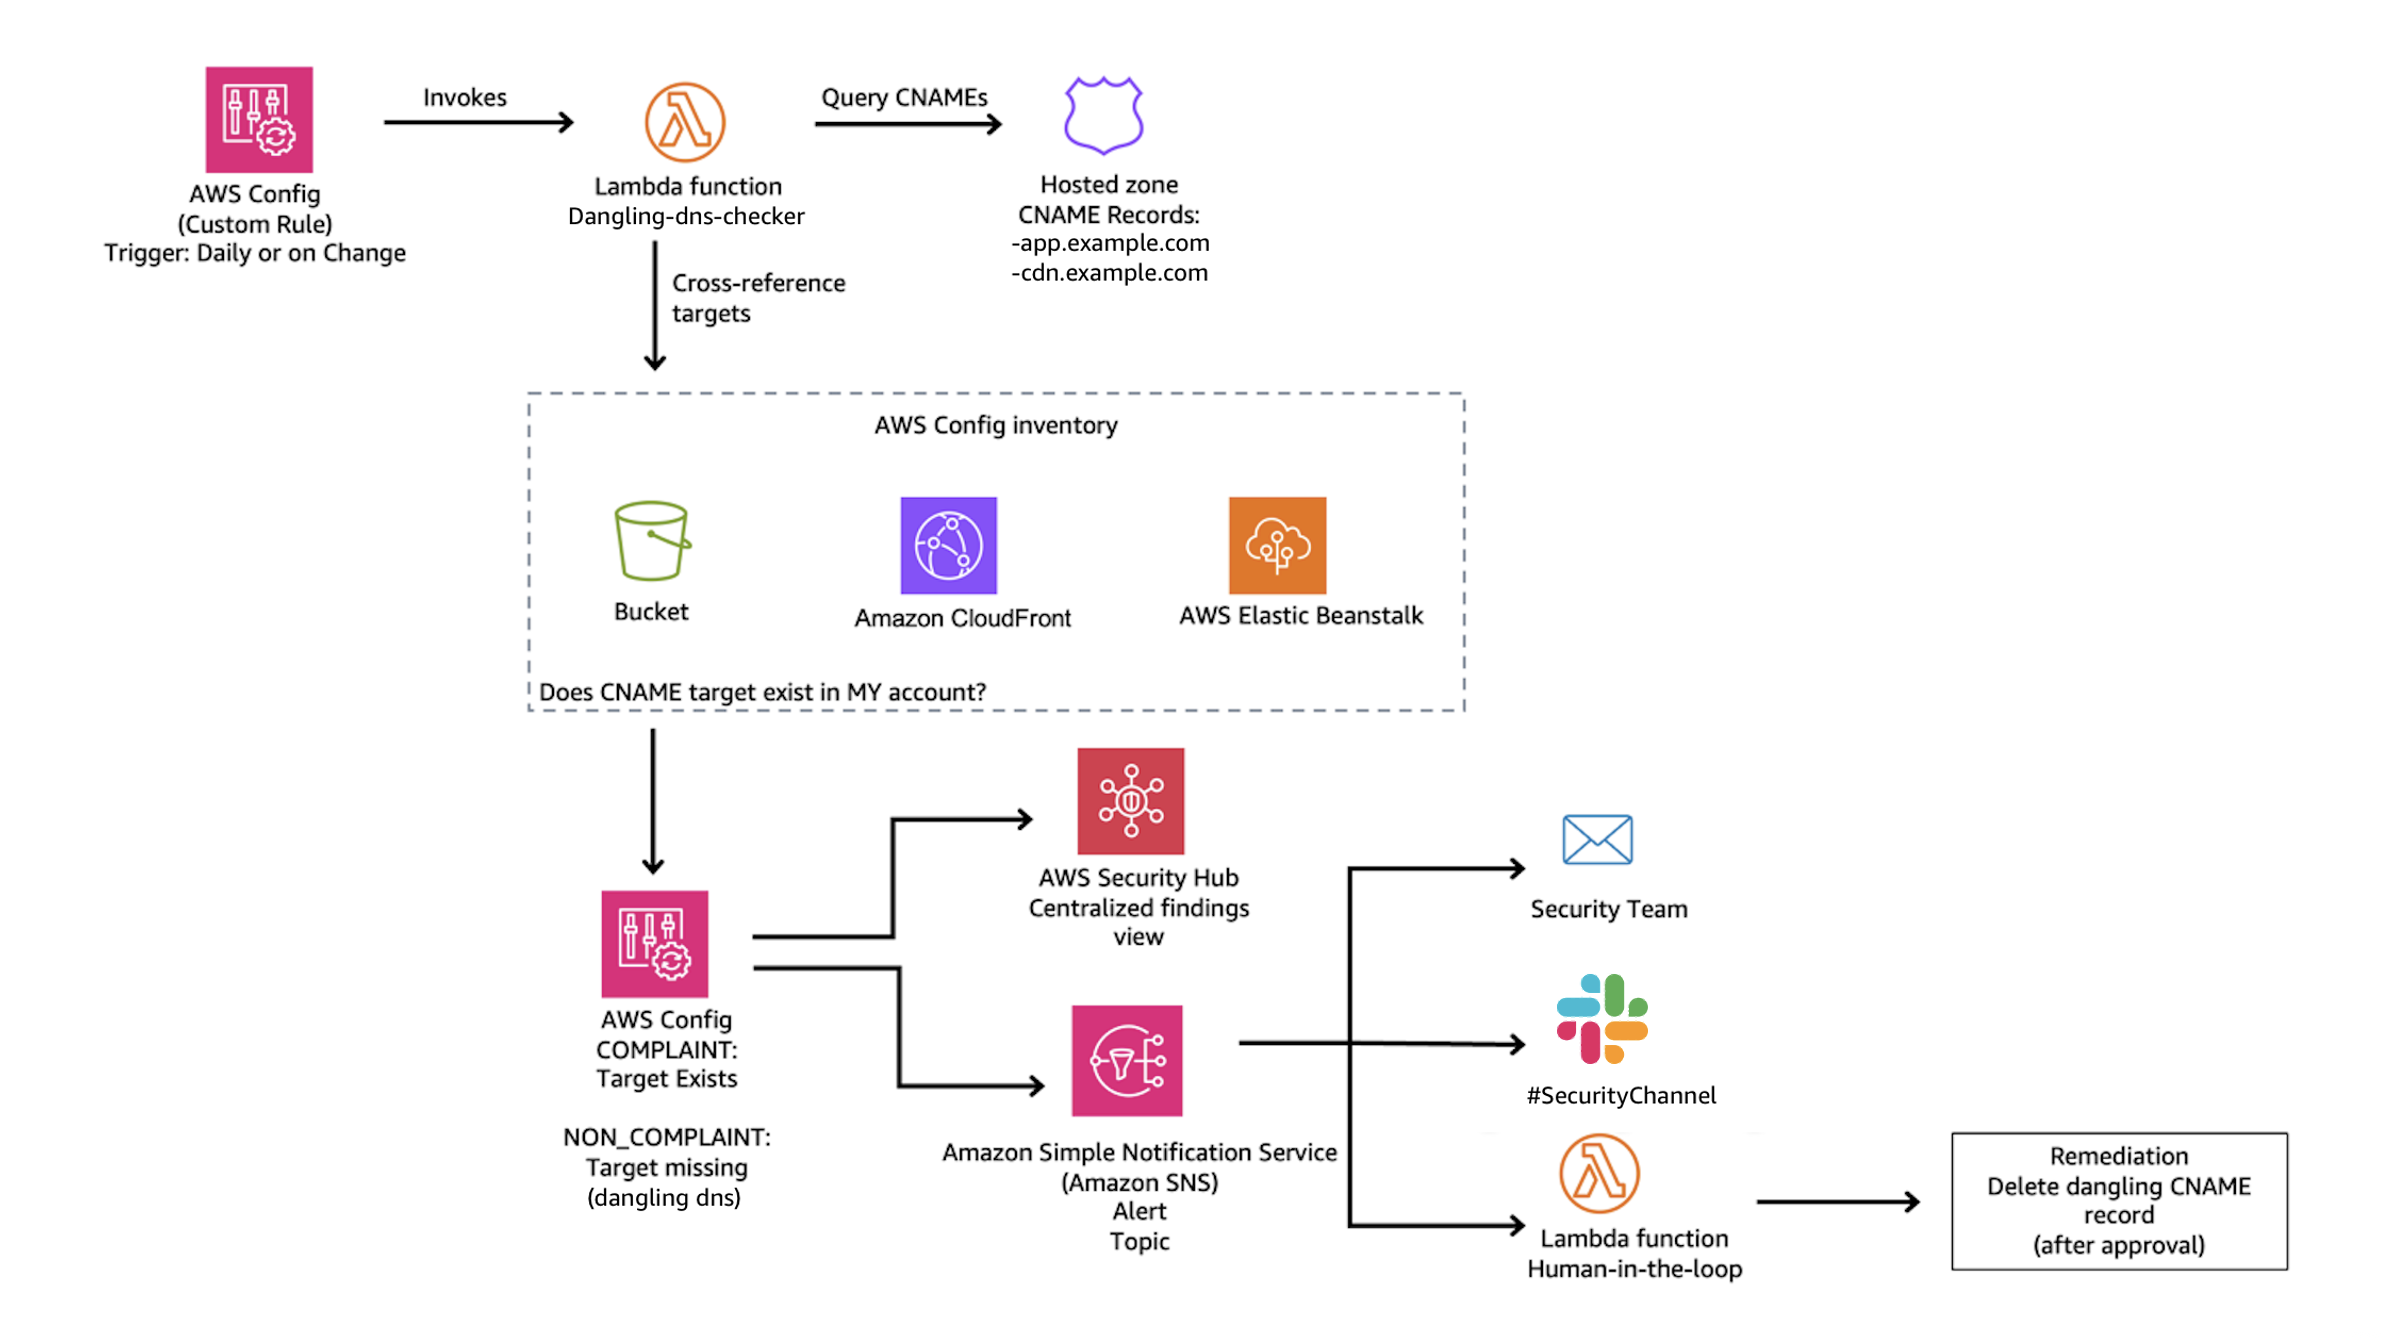
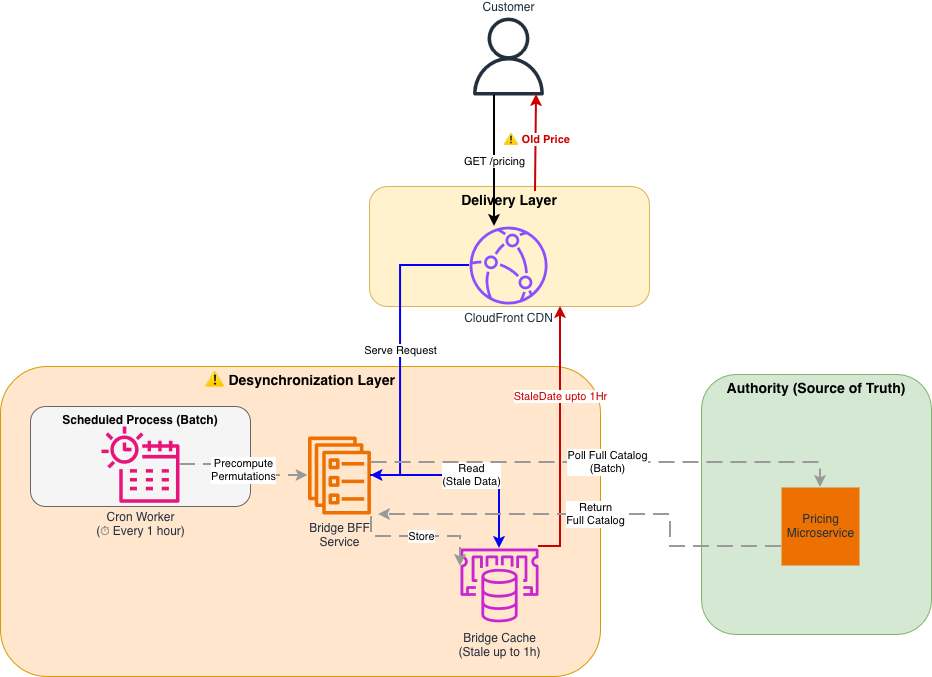

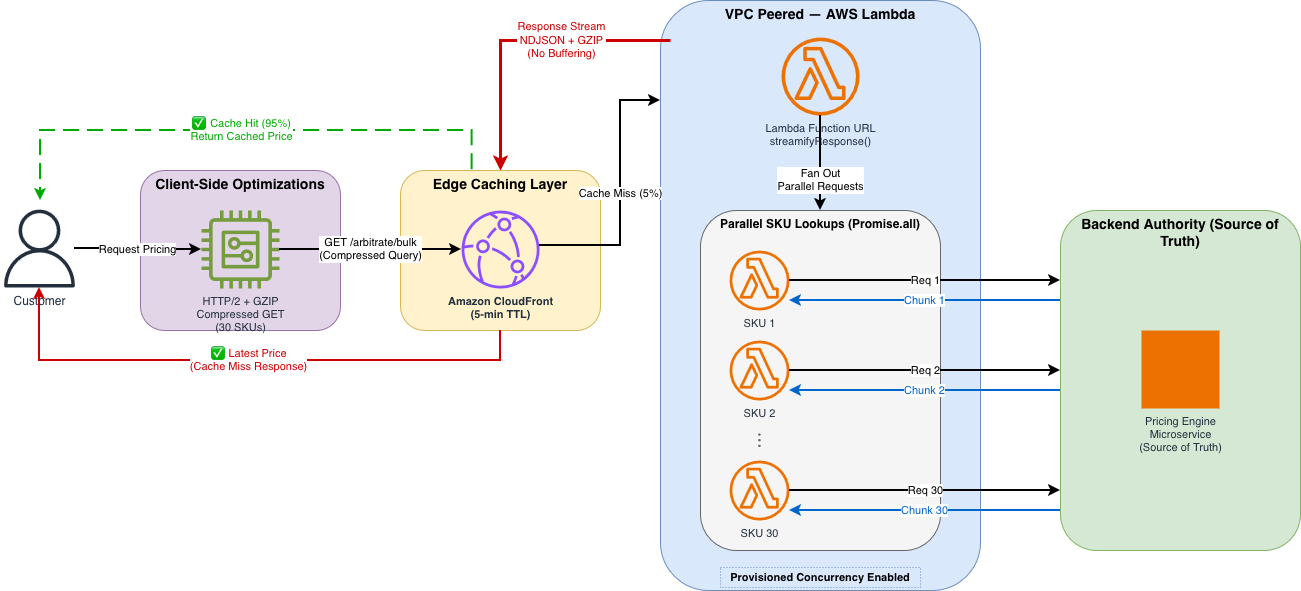
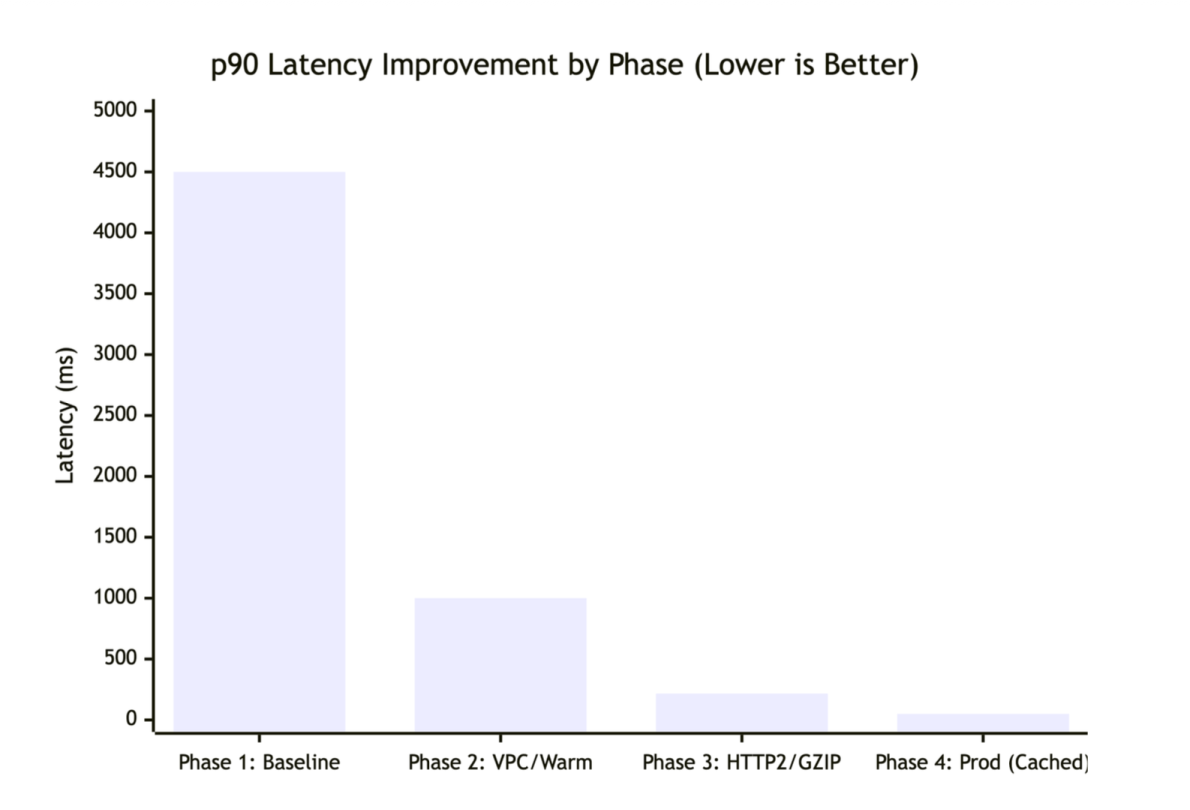
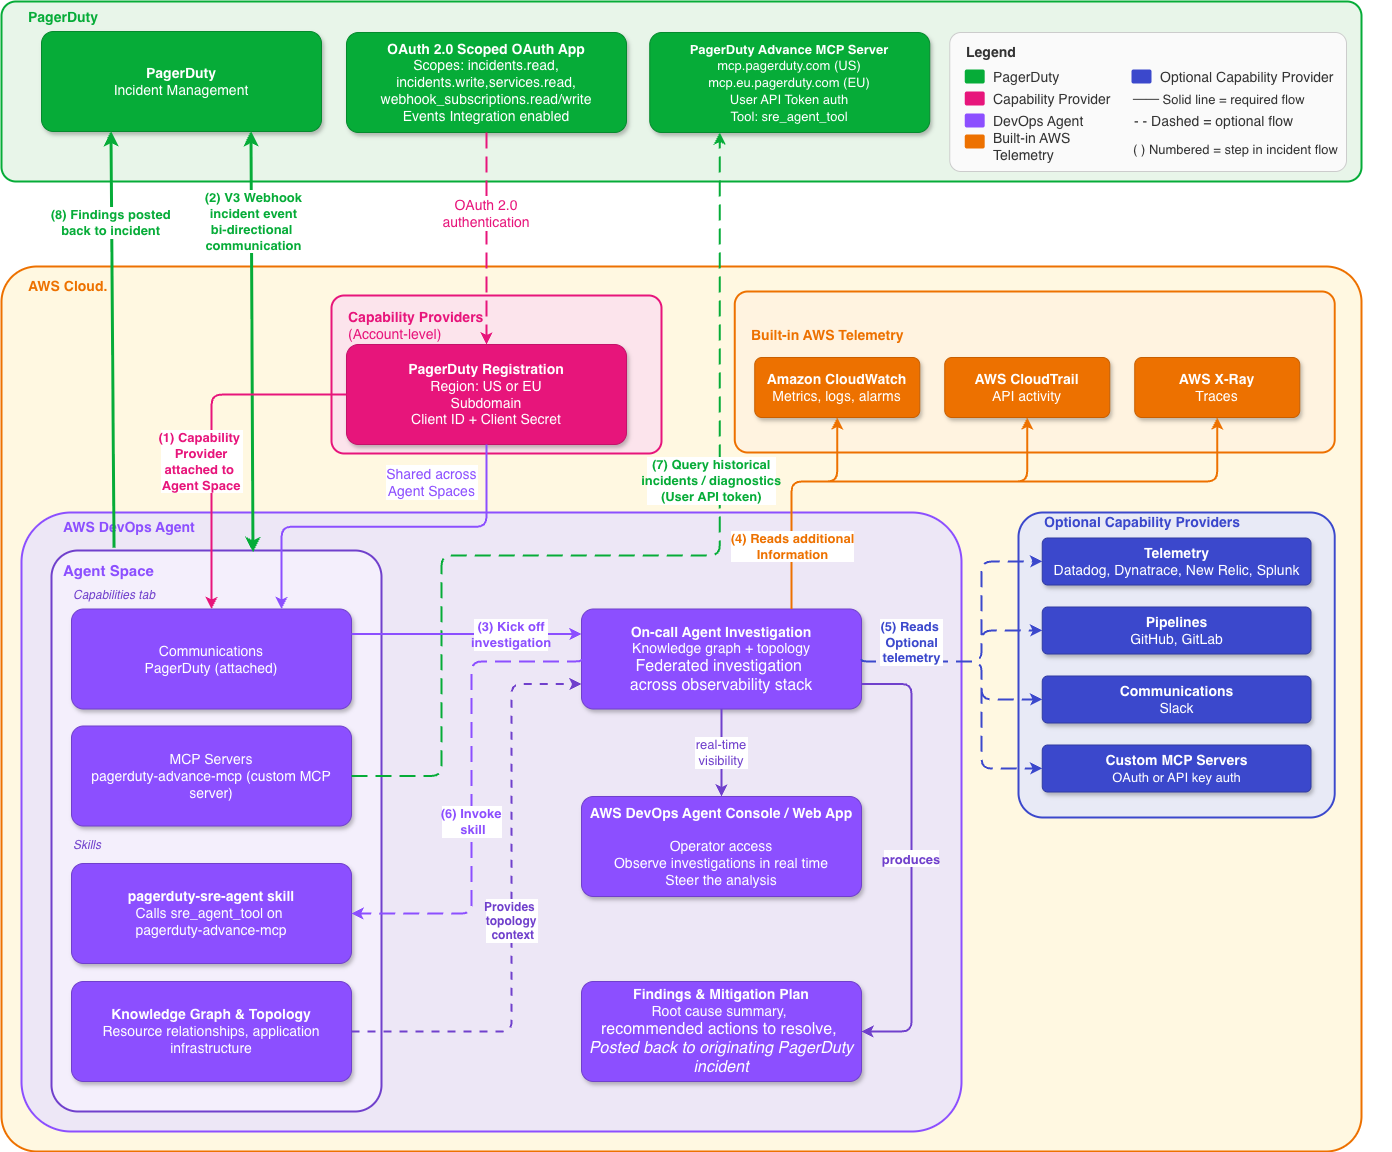
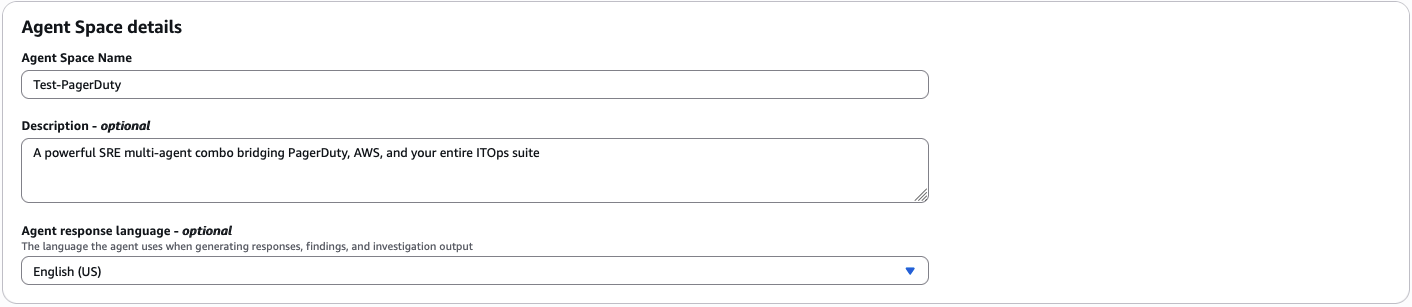
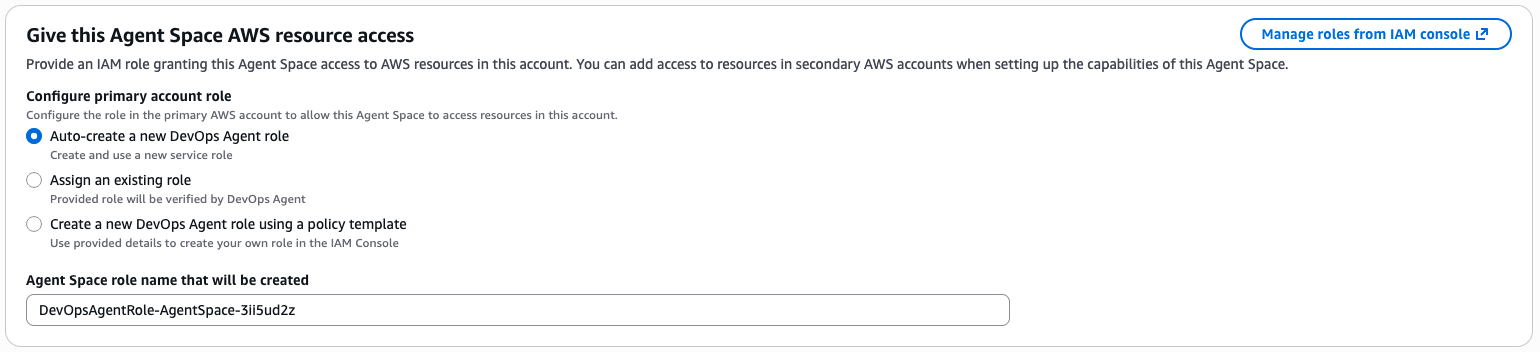
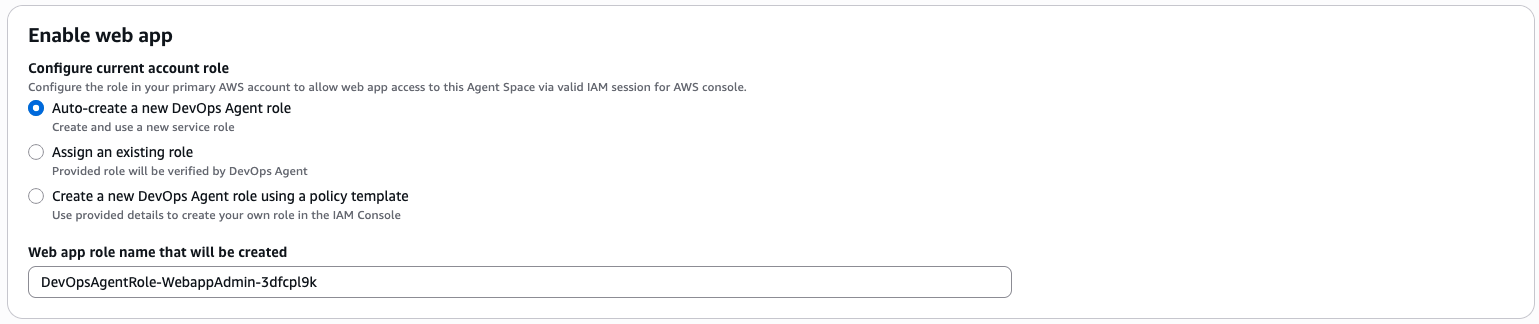
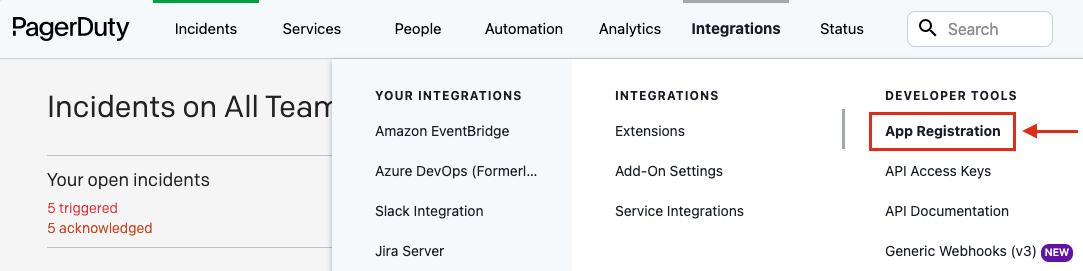
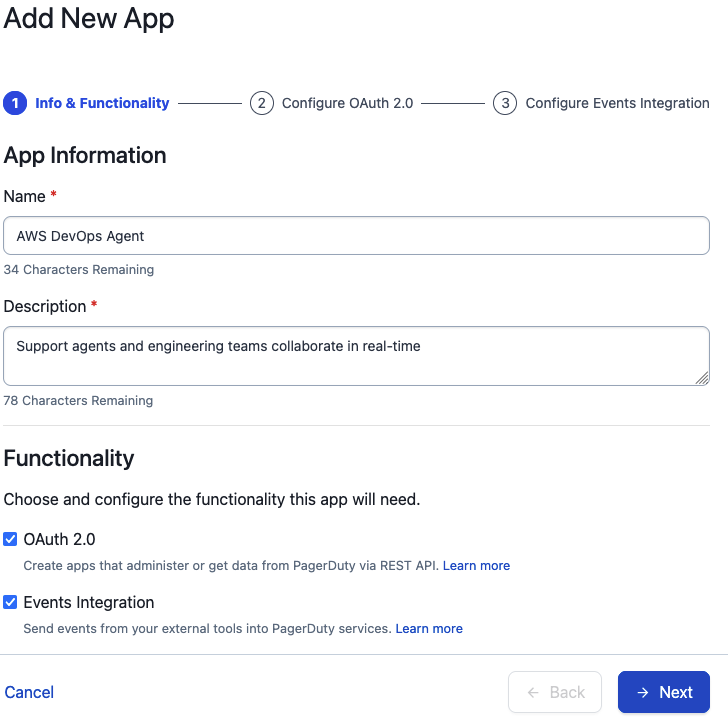
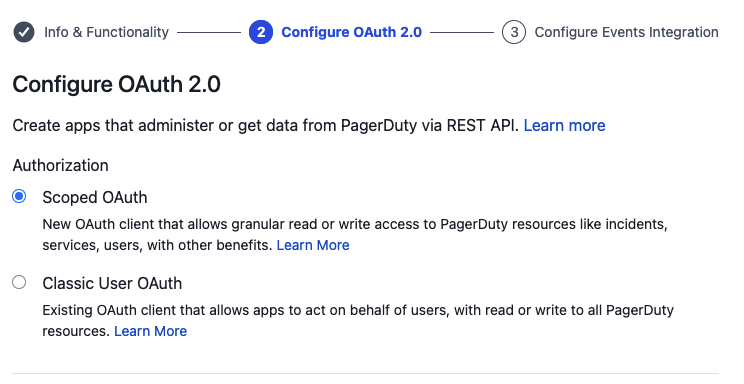
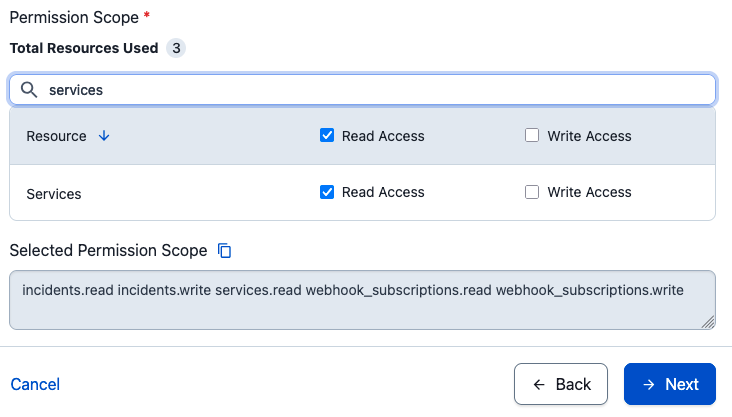
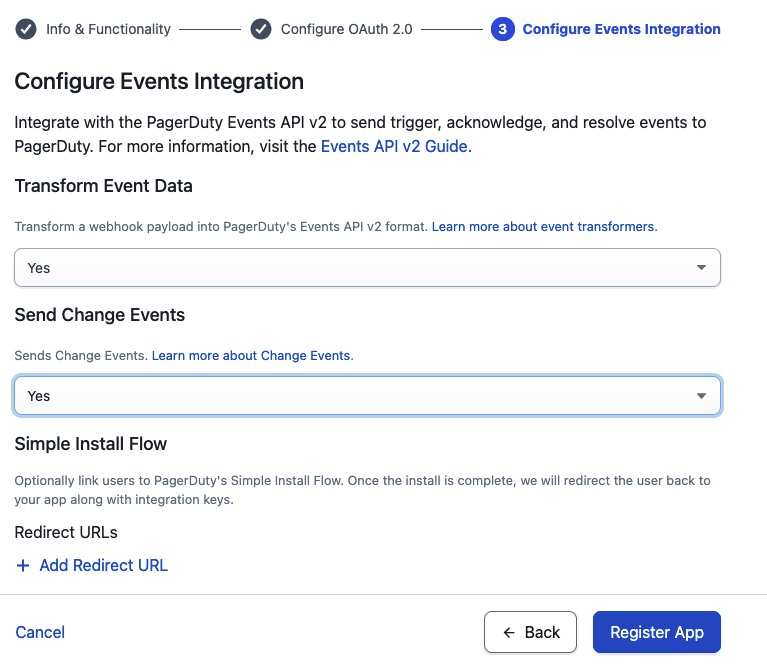
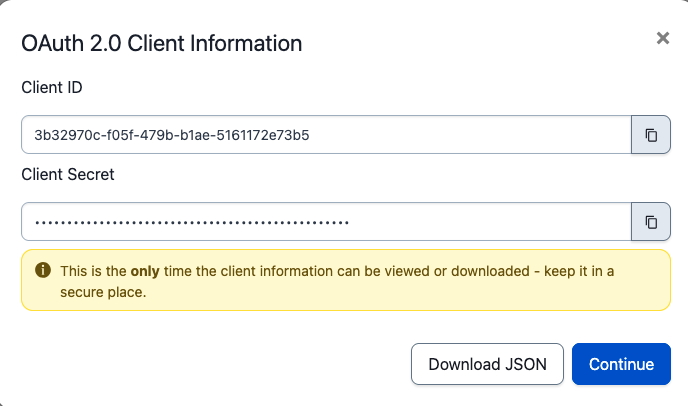

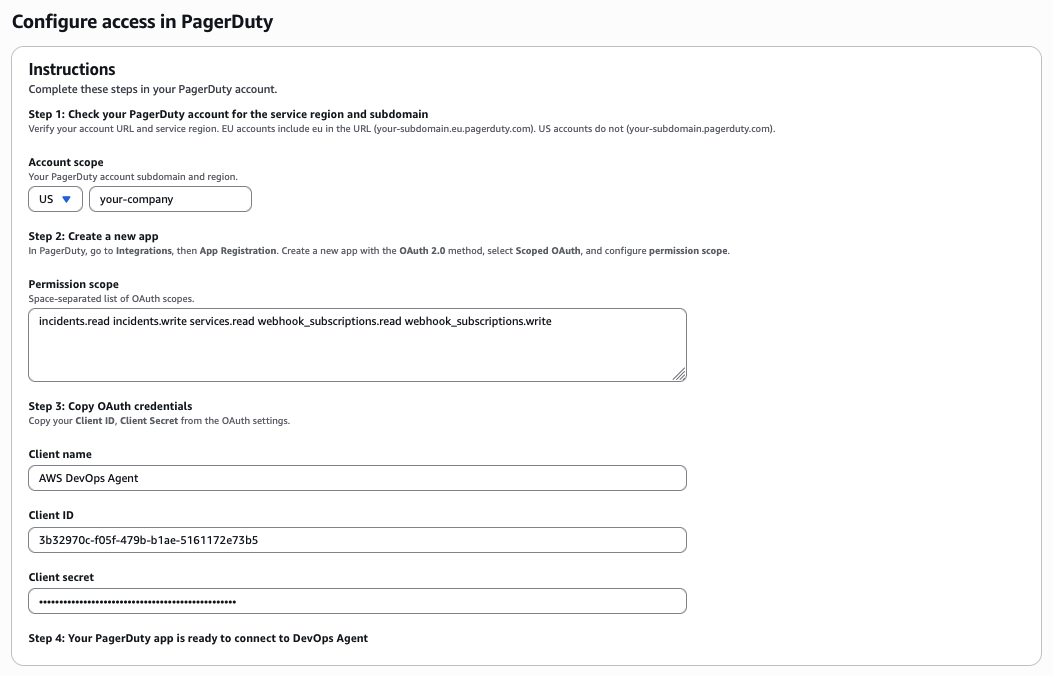
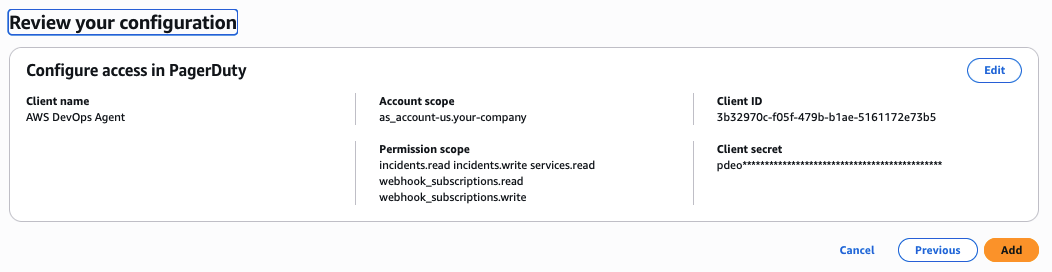
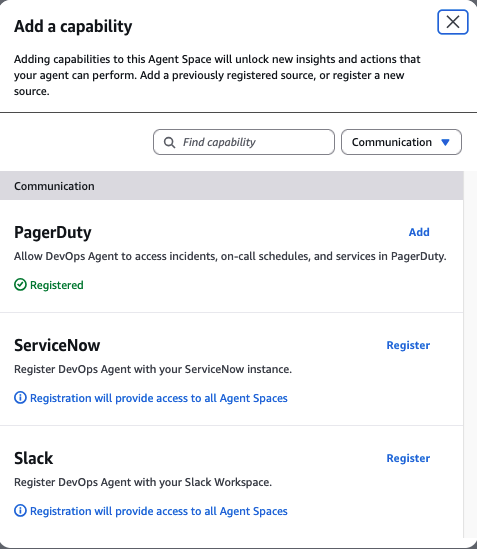
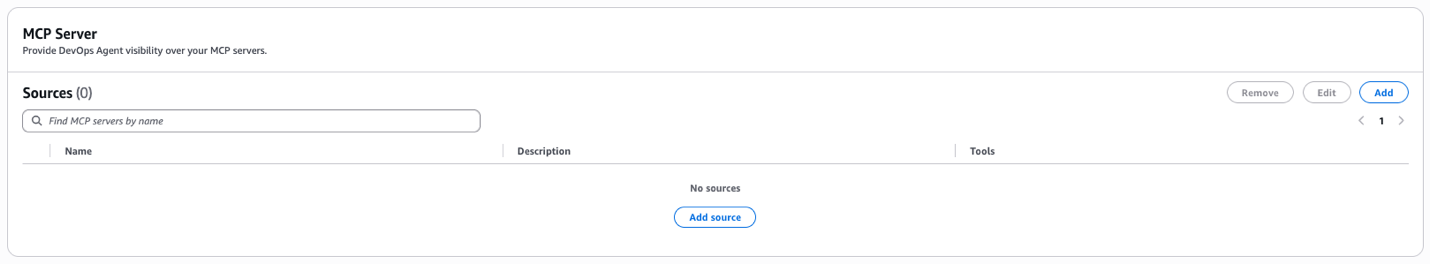
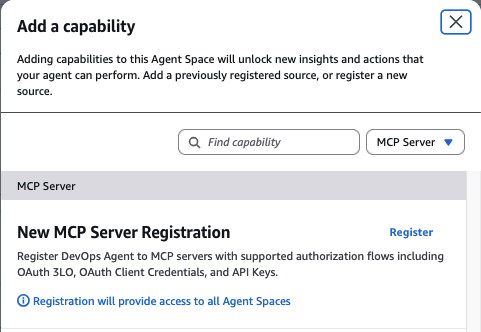
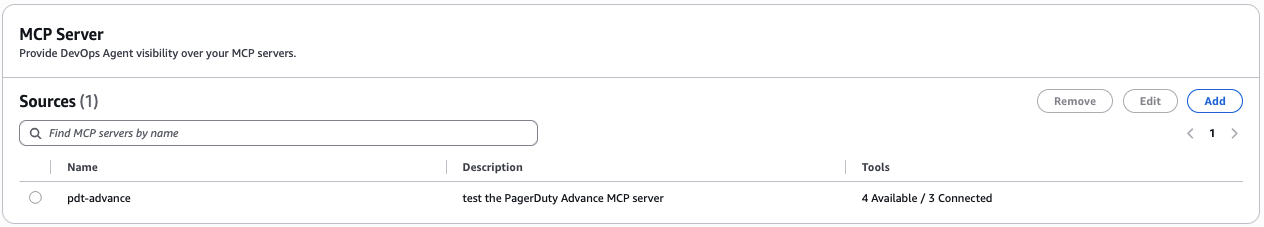

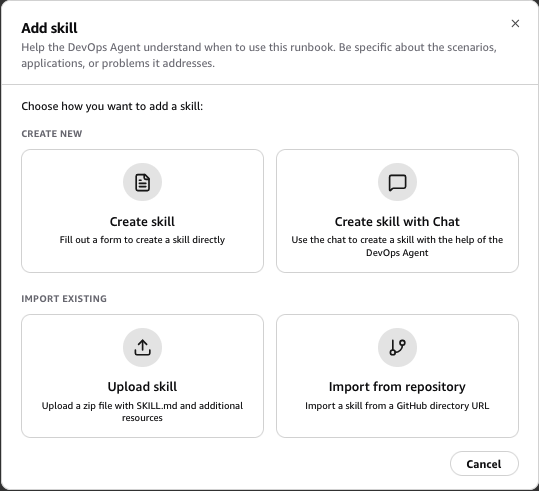
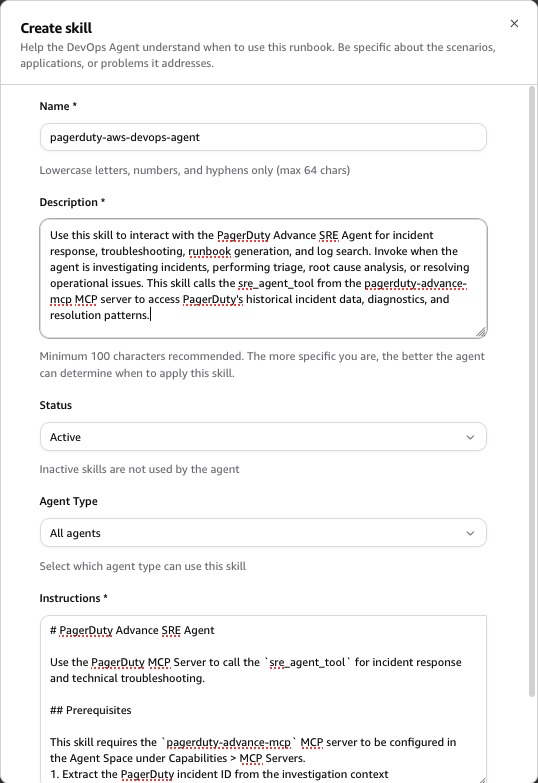
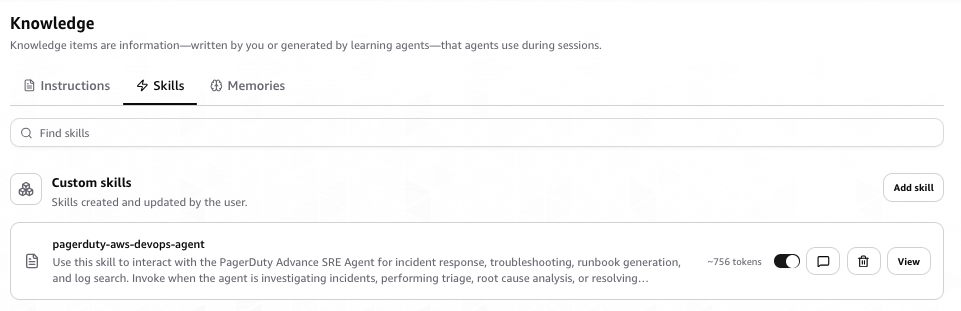
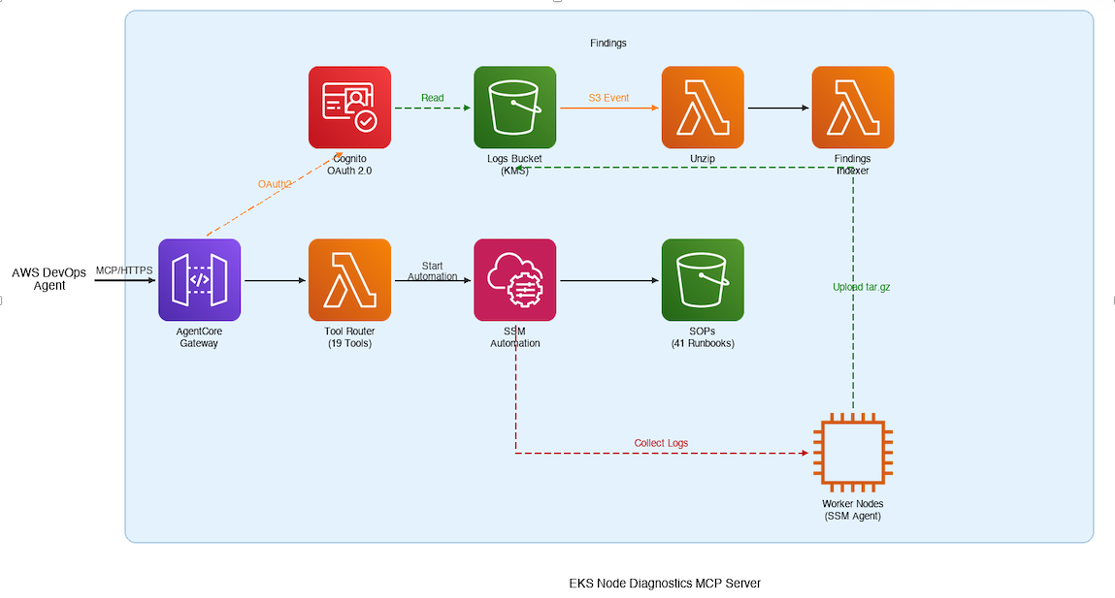
 WARNING: The following commands will disrupt DNS resolution for all pods on the target node. Only run these in a non-production test environment. Do not execute on production nodes.